diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers-5.3.0.dist-info/INSTALLER b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers-5.3.0.dist-info/INSTALLER new file mode 100644 index 0000000000000000000000000000000000000000..a1b589e38a32041e49332e5e81c2d363dc418d68 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers-5.3.0.dist-info/INSTALLER @@ -0,0 +1 @@ +pip diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers-5.3.0.dist-info/METADATA b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers-5.3.0.dist-info/METADATA new file mode 100644 index 0000000000000000000000000000000000000000..1641f0c76e7e357c007fc254e28b691791bc6e93 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers-5.3.0.dist-info/METADATA @@ -0,0 +1,648 @@ +Metadata-Version: 2.4 +Name: transformers +Version: 5.3.0 +Summary: Transformers: the model-definition framework for state-of-the-art machine learning models in text, vision, audio, and multimodal models, for both inference and training. +Home-page: https://github.com/huggingface/transformers +Author: The Hugging Face team (past and future) with the help of all our contributors (https://github.com/huggingface/transformers/graphs/contributors) +Author-email: transformers@huggingface.co +License: Apache 2.0 License +Keywords: machine-learning nlp python pytorch transformer llm vlm deep-learning inference training model-hub pretrained-models llama gemma qwen +Classifier: Development Status :: 5 - Production/Stable +Classifier: Intended Audience :: Developers +Classifier: Intended Audience :: Education +Classifier: Intended Audience :: Science/Research +Classifier: Operating System :: OS Independent +Classifier: Programming Language :: Python :: 3 +Classifier: Programming Language :: Python :: 3.10 +Classifier: Programming Language :: Python :: 3.11 +Classifier: Programming Language :: Python :: 3.12 +Classifier: Programming Language :: Python :: 3.13 +Classifier: Programming Language :: Python :: 3.14 +Classifier: Topic :: Scientific/Engineering :: Artificial Intelligence +Requires-Python: >=3.10.0 +Description-Content-Type: text/markdown +License-File: LICENSE +Requires-Dist: huggingface-hub<2.0,>=1.3.0 +Requires-Dist: numpy>=1.17 +Requires-Dist: packaging>=20.0 +Requires-Dist: pyyaml>=5.1 +Requires-Dist: regex!=2019.12.17 +Requires-Dist: tokenizers<=0.23.0,>=0.22.0 +Requires-Dist: typer +Requires-Dist: safetensors>=0.4.3 +Requires-Dist: tqdm>=4.27 +Provides-Extra: torch +Requires-Dist: torch>=2.4; extra == "torch" +Requires-Dist: accelerate>=1.1.0; extra == "torch" +Provides-Extra: vision +Requires-Dist: torchvision; extra == "vision" +Requires-Dist: Pillow<=15.0,>=10.0.1; extra == "vision" +Provides-Extra: audio +Requires-Dist: torchaudio; extra == "audio" +Requires-Dist: librosa; extra == "audio" +Requires-Dist: pyctcdecode>=0.4.0; extra == "audio" +Requires-Dist: phonemizer; extra == "audio" +Provides-Extra: video +Requires-Dist: av; extra == "video" +Provides-Extra: timm +Requires-Dist: timm>=1.0.23; extra == "timm" +Provides-Extra: quality +Requires-Dist: datasets>=2.15.0; extra == "quality" +Requires-Dist: ruff==0.14.10; extra == "quality" +Requires-Dist: GitPython<3.1.19; extra == "quality" +Requires-Dist: urllib3<2.0.0; extra == "quality" +Requires-Dist: libcst; extra == "quality" +Requires-Dist: rich; extra == "quality" +Requires-Dist: ty==0.0.12; extra == "quality" +Provides-Extra: kernels +Requires-Dist: kernels<0.11,>=0.10.2; extra == "kernels" +Provides-Extra: sentencepiece +Requires-Dist: sentencepiece!=0.1.92,>=0.1.91; extra == "sentencepiece" +Requires-Dist: protobuf; extra == "sentencepiece" +Provides-Extra: tiktoken +Requires-Dist: tiktoken; extra == "tiktoken" +Requires-Dist: blobfile; extra == "tiktoken" +Provides-Extra: mistral-common +Requires-Dist: mistral-common[image]>=1.8.8; extra == "mistral-common" +Provides-Extra: chat-template +Requires-Dist: jinja2>=3.1.0; extra == "chat-template" +Requires-Dist: jmespath>=1.0.1; extra == "chat-template" +Provides-Extra: sklearn +Requires-Dist: scikit-learn; extra == "sklearn" +Provides-Extra: accelerate +Requires-Dist: accelerate>=1.1.0; extra == "accelerate" +Provides-Extra: retrieval +Requires-Dist: faiss-cpu; extra == "retrieval" +Requires-Dist: datasets>=2.15.0; extra == "retrieval" +Provides-Extra: sagemaker +Requires-Dist: sagemaker>=2.31.0; extra == "sagemaker" +Provides-Extra: deepspeed +Requires-Dist: deepspeed>=0.9.3; extra == "deepspeed" +Requires-Dist: accelerate>=1.1.0; extra == "deepspeed" +Provides-Extra: optuna +Requires-Dist: optuna; extra == "optuna" +Provides-Extra: integrations +Requires-Dist: kernels<0.11,>=0.10.2; extra == "integrations" +Requires-Dist: optuna; extra == "integrations" +Requires-Dist: codecarbon>=2.8.1; extra == "integrations" +Requires-Dist: ray[tune]>=2.7.0; extra == "integrations" +Provides-Extra: ray +Requires-Dist: ray[tune]>=2.7.0; extra == "ray" +Provides-Extra: codecarbon +Requires-Dist: codecarbon>=2.8.1; extra == "codecarbon" +Provides-Extra: serving +Requires-Dist: openai>=1.98.0; extra == "serving" +Requires-Dist: pydantic>=2; extra == "serving" +Requires-Dist: uvicorn; extra == "serving" +Requires-Dist: fastapi; extra == "serving" +Requires-Dist: starlette; extra == "serving" +Requires-Dist: rich; extra == "serving" +Requires-Dist: torch>=2.4; extra == "serving" +Requires-Dist: accelerate>=1.1.0; extra == "serving" +Provides-Extra: num2words +Requires-Dist: num2words; extra == "num2words" +Provides-Extra: benchmark +Requires-Dist: optimum-benchmark>=0.3.0; extra == "benchmark" +Provides-Extra: ja +Requires-Dist: fugashi>=1.0; extra == "ja" +Requires-Dist: ipadic<2.0,>=1.0.0; extra == "ja" +Requires-Dist: unidic_lite>=1.0.7; extra == "ja" +Requires-Dist: unidic>=1.0.2; extra == "ja" +Requires-Dist: rhoknp<1.3.1,>=1.1.0; extra == "ja" +Requires-Dist: sudachipy>=0.6.6; extra == "ja" +Requires-Dist: sudachidict_core>=20220729; extra == "ja" +Provides-Extra: open-telemetry +Requires-Dist: opentelemetry-api; extra == "open-telemetry" +Requires-Dist: opentelemetry-exporter-otlp; extra == "open-telemetry" +Requires-Dist: opentelemetry-sdk; extra == "open-telemetry" +Provides-Extra: testing +Requires-Dist: pytest<9.0.0,>=7.2.0; extra == "testing" +Requires-Dist: pytest-asyncio>=1.2.0; extra == "testing" +Requires-Dist: pytest-random-order; extra == "testing" +Requires-Dist: pytest-rich; extra == "testing" +Requires-Dist: pytest-xdist; extra == "testing" +Requires-Dist: pytest-order; extra == "testing" +Requires-Dist: pytest-rerunfailures<16.0; extra == "testing" +Requires-Dist: pytest-timeout; extra == "testing" +Requires-Dist: pytest-env; extra == "testing" +Requires-Dist: timeout-decorator; extra == "testing" +Requires-Dist: parameterized>=0.9; extra == "testing" +Requires-Dist: psutil; extra == "testing" +Requires-Dist: dill<0.3.5; extra == "testing" +Requires-Dist: evaluate>=0.4.6; extra == "testing" +Requires-Dist: rouge-score!=0.0.7,!=0.0.8,!=0.1,!=0.1.1; extra == "testing" +Requires-Dist: nltk<=3.8.1; extra == "testing" +Requires-Dist: sacremoses; extra == "testing" +Requires-Dist: rjieba; extra == "testing" +Requires-Dist: beautifulsoup4; extra == "testing" +Requires-Dist: tensorboard; extra == "testing" +Requires-Dist: sacrebleu<2.0.0,>=1.4.12; extra == "testing" +Requires-Dist: filelock; extra == "testing" +Requires-Dist: datasets>=2.15.0; extra == "testing" +Requires-Dist: ruff==0.14.10; extra == "testing" +Requires-Dist: GitPython<3.1.19; extra == "testing" +Requires-Dist: urllib3<2.0.0; extra == "testing" +Requires-Dist: libcst; extra == "testing" +Requires-Dist: rich; extra == "testing" +Requires-Dist: ty==0.0.12; extra == "testing" +Requires-Dist: faiss-cpu; extra == "testing" +Requires-Dist: datasets>=2.15.0; extra == "testing" +Requires-Dist: sentencepiece!=0.1.92,>=0.1.91; extra == "testing" +Requires-Dist: protobuf; extra == "testing" +Requires-Dist: openai>=1.98.0; extra == "testing" +Requires-Dist: pydantic>=2; extra == "testing" +Requires-Dist: uvicorn; extra == "testing" +Requires-Dist: fastapi; extra == "testing" +Requires-Dist: starlette; extra == "testing" +Requires-Dist: rich; extra == "testing" +Requires-Dist: torch>=2.4; extra == "testing" +Requires-Dist: accelerate>=1.1.0; extra == "testing" +Requires-Dist: mistral-common[image]>=1.8.8; extra == "testing" +Provides-Extra: deepspeed-testing +Requires-Dist: deepspeed>=0.9.3; extra == "deepspeed-testing" +Requires-Dist: accelerate>=1.1.0; extra == "deepspeed-testing" +Requires-Dist: pytest<9.0.0,>=7.2.0; extra == "deepspeed-testing" +Requires-Dist: pytest-asyncio>=1.2.0; extra == "deepspeed-testing" +Requires-Dist: pytest-random-order; extra == "deepspeed-testing" +Requires-Dist: pytest-rich; extra == "deepspeed-testing" +Requires-Dist: pytest-xdist; extra == "deepspeed-testing" +Requires-Dist: pytest-order; extra == "deepspeed-testing" +Requires-Dist: pytest-rerunfailures<16.0; extra == "deepspeed-testing" +Requires-Dist: pytest-timeout; extra == "deepspeed-testing" +Requires-Dist: pytest-env; extra == "deepspeed-testing" +Requires-Dist: timeout-decorator; extra == "deepspeed-testing" +Requires-Dist: parameterized>=0.9; extra == "deepspeed-testing" +Requires-Dist: psutil; extra == "deepspeed-testing" +Requires-Dist: dill<0.3.5; extra == "deepspeed-testing" +Requires-Dist: evaluate>=0.4.6; extra == "deepspeed-testing" +Requires-Dist: rouge-score!=0.0.7,!=0.0.8,!=0.1,!=0.1.1; extra == "deepspeed-testing" +Requires-Dist: nltk<=3.8.1; extra == "deepspeed-testing" +Requires-Dist: sacremoses; extra == "deepspeed-testing" +Requires-Dist: rjieba; extra == "deepspeed-testing" +Requires-Dist: beautifulsoup4; extra == "deepspeed-testing" +Requires-Dist: tensorboard; extra == "deepspeed-testing" +Requires-Dist: sacrebleu<2.0.0,>=1.4.12; extra == "deepspeed-testing" +Requires-Dist: filelock; extra == "deepspeed-testing" +Requires-Dist: datasets>=2.15.0; extra == "deepspeed-testing" +Requires-Dist: ruff==0.14.10; extra == "deepspeed-testing" +Requires-Dist: GitPython<3.1.19; extra == "deepspeed-testing" +Requires-Dist: urllib3<2.0.0; extra == "deepspeed-testing" +Requires-Dist: libcst; extra == "deepspeed-testing" +Requires-Dist: rich; extra == "deepspeed-testing" +Requires-Dist: ty==0.0.12; extra == "deepspeed-testing" +Requires-Dist: faiss-cpu; extra == "deepspeed-testing" +Requires-Dist: datasets>=2.15.0; extra == "deepspeed-testing" +Requires-Dist: sentencepiece!=0.1.92,>=0.1.91; extra == "deepspeed-testing" +Requires-Dist: protobuf; extra == "deepspeed-testing" +Requires-Dist: openai>=1.98.0; extra == "deepspeed-testing" +Requires-Dist: pydantic>=2; extra == "deepspeed-testing" +Requires-Dist: uvicorn; extra == "deepspeed-testing" +Requires-Dist: fastapi; extra == "deepspeed-testing" +Requires-Dist: starlette; extra == "deepspeed-testing" +Requires-Dist: rich; extra == "deepspeed-testing" +Requires-Dist: torch>=2.4; extra == "deepspeed-testing" +Requires-Dist: accelerate>=1.1.0; extra == "deepspeed-testing" +Requires-Dist: mistral-common[image]>=1.8.8; extra == "deepspeed-testing" +Requires-Dist: optuna; extra == "deepspeed-testing" +Requires-Dist: sentencepiece!=0.1.92,>=0.1.91; extra == "deepspeed-testing" +Requires-Dist: protobuf; extra == "deepspeed-testing" +Provides-Extra: all +Requires-Dist: torch>=2.4; extra == "all" +Requires-Dist: accelerate>=1.1.0; extra == "all" +Requires-Dist: torchvision; extra == "all" +Requires-Dist: Pillow<=15.0,>=10.0.1; extra == "all" +Requires-Dist: torchaudio; extra == "all" +Requires-Dist: librosa; extra == "all" +Requires-Dist: pyctcdecode>=0.4.0; extra == "all" +Requires-Dist: phonemizer; extra == "all" +Requires-Dist: av; extra == "all" +Requires-Dist: kernels<0.11,>=0.10.2; extra == "all" +Requires-Dist: timm>=1.0.23; extra == "all" +Requires-Dist: sentencepiece!=0.1.92,>=0.1.91; extra == "all" +Requires-Dist: protobuf; extra == "all" +Requires-Dist: tiktoken; extra == "all" +Requires-Dist: blobfile; extra == "all" +Requires-Dist: jinja2>=3.1.0; extra == "all" +Requires-Dist: jmespath>=1.0.1; extra == "all" +Requires-Dist: num2words; extra == "all" +Requires-Dist: mistral-common[image]>=1.8.8; extra == "all" +Provides-Extra: dev +Requires-Dist: torch>=2.4; extra == "dev" +Requires-Dist: accelerate>=1.1.0; extra == "dev" +Requires-Dist: torchvision; extra == "dev" +Requires-Dist: Pillow<=15.0,>=10.0.1; extra == "dev" +Requires-Dist: torchaudio; extra == "dev" +Requires-Dist: librosa; extra == "dev" +Requires-Dist: pyctcdecode>=0.4.0; extra == "dev" +Requires-Dist: phonemizer; extra == "dev" +Requires-Dist: av; extra == "dev" +Requires-Dist: kernels<0.11,>=0.10.2; extra == "dev" +Requires-Dist: timm>=1.0.23; extra == "dev" +Requires-Dist: sentencepiece!=0.1.92,>=0.1.91; extra == "dev" +Requires-Dist: protobuf; extra == "dev" +Requires-Dist: tiktoken; extra == "dev" +Requires-Dist: blobfile; extra == "dev" +Requires-Dist: jinja2>=3.1.0; extra == "dev" +Requires-Dist: jmespath>=1.0.1; extra == "dev" +Requires-Dist: num2words; extra == "dev" +Requires-Dist: mistral-common[image]>=1.8.8; extra == "dev" +Requires-Dist: pytest<9.0.0,>=7.2.0; extra == "dev" +Requires-Dist: pytest-asyncio>=1.2.0; extra == "dev" +Requires-Dist: pytest-random-order; extra == "dev" +Requires-Dist: pytest-rich; extra == "dev" +Requires-Dist: pytest-xdist; extra == "dev" +Requires-Dist: pytest-order; extra == "dev" +Requires-Dist: pytest-rerunfailures<16.0; extra == "dev" +Requires-Dist: pytest-timeout; extra == "dev" +Requires-Dist: pytest-env; extra == "dev" +Requires-Dist: timeout-decorator; extra == "dev" +Requires-Dist: parameterized>=0.9; extra == "dev" +Requires-Dist: psutil; extra == "dev" +Requires-Dist: dill<0.3.5; extra == "dev" +Requires-Dist: evaluate>=0.4.6; extra == "dev" +Requires-Dist: rouge-score!=0.0.7,!=0.0.8,!=0.1,!=0.1.1; extra == "dev" +Requires-Dist: nltk<=3.8.1; extra == "dev" +Requires-Dist: sacremoses; extra == "dev" +Requires-Dist: rjieba; extra == "dev" +Requires-Dist: beautifulsoup4; extra == "dev" +Requires-Dist: tensorboard; extra == "dev" +Requires-Dist: sacrebleu<2.0.0,>=1.4.12; extra == "dev" +Requires-Dist: filelock; extra == "dev" +Requires-Dist: datasets>=2.15.0; extra == "dev" +Requires-Dist: ruff==0.14.10; extra == "dev" +Requires-Dist: GitPython<3.1.19; extra == "dev" +Requires-Dist: urllib3<2.0.0; extra == "dev" +Requires-Dist: libcst; extra == "dev" +Requires-Dist: rich; extra == "dev" +Requires-Dist: ty==0.0.12; extra == "dev" +Requires-Dist: faiss-cpu; extra == "dev" +Requires-Dist: datasets>=2.15.0; extra == "dev" +Requires-Dist: sentencepiece!=0.1.92,>=0.1.91; extra == "dev" +Requires-Dist: protobuf; extra == "dev" +Requires-Dist: openai>=1.98.0; extra == "dev" +Requires-Dist: pydantic>=2; extra == "dev" +Requires-Dist: uvicorn; extra == "dev" +Requires-Dist: fastapi; extra == "dev" +Requires-Dist: starlette; extra == "dev" +Requires-Dist: rich; extra == "dev" +Requires-Dist: torch>=2.4; extra == "dev" +Requires-Dist: accelerate>=1.1.0; extra == "dev" +Requires-Dist: mistral-common[image]>=1.8.8; extra == "dev" +Requires-Dist: fugashi>=1.0; extra == "dev" +Requires-Dist: ipadic<2.0,>=1.0.0; extra == "dev" +Requires-Dist: unidic_lite>=1.0.7; extra == "dev" +Requires-Dist: unidic>=1.0.2; extra == "dev" +Requires-Dist: rhoknp<1.3.1,>=1.1.0; extra == "dev" +Requires-Dist: sudachipy>=0.6.6; extra == "dev" +Requires-Dist: sudachidict_core>=20220729; extra == "dev" +Requires-Dist: scikit-learn; extra == "dev" +Dynamic: author +Dynamic: author-email +Dynamic: classifier +Dynamic: description +Dynamic: description-content-type +Dynamic: home-page +Dynamic: keywords +Dynamic: license +Dynamic: license-file +Dynamic: provides-extra +Dynamic: requires-dist +Dynamic: requires-python +Dynamic: summary + + + +

+ + + + Hugging Face Transformers Library + +
+
+

+ +

+ Checkpoints on Hub + Build + GitHub + Documentation + GitHub release + Contributor Covenant + DOI +

+ +

+

+ English | + 简体中文 | + 繁體中文 | + 한국어 | + Español | + 日本語 | + हिन्दी | + Русский | + Português | + తెలుగు | + Français | + Deutsch | + Italiano | + Tiếng Việt | + العربية | + اردو | + বাংলা | +

+

+ +

+

State-of-the-art pretrained models for inference and training

+

+ +

+ +

+ +Transformers acts as the model-definition framework for state-of-the-art machine learning with text, computer +vision, audio, video, and multimodal models, for both inference and training. + +It centralizes the model definition so that this definition is agreed upon across the ecosystem. `transformers` is the +pivot across frameworks: if a model definition is supported, it will be compatible with the majority of training +frameworks (Axolotl, Unsloth, DeepSpeed, FSDP, PyTorch-Lightning, ...), inference engines (vLLM, SGLang, TGI, ...), +and adjacent modeling libraries (llama.cpp, mlx, ...) which leverage the model definition from `transformers`. + +We pledge to help support new state-of-the-art models and democratize their usage by having their model definition be +simple, customizable, and efficient. + +There are over 1M+ Transformers [model checkpoints](https://huggingface.co/models?library=transformers&sort=trending) on the [Hugging Face Hub](https://huggingface.com/models) you can use. + +Explore the [Hub](https://huggingface.com/) today to find a model and use Transformers to help you get started right away. + +## Installation + +Transformers works with Python 3.10+, and [PyTorch](https://pytorch.org/get-started/locally/) 2.4+. + +Create and activate a virtual environment with [venv](https://docs.python.org/3/library/venv.html) or [uv](https://docs.astral.sh/uv/), a fast Rust-based Python package and project manager. + +```py +# venv +python -m venv .my-env +source .my-env/bin/activate +# uv +uv venv .my-env +source .my-env/bin/activate +``` + +Install Transformers in your virtual environment. + +```py +# pip +pip install "transformers[torch]" + +# uv +uv pip install "transformers[torch]" +``` + +Install Transformers from source if you want the latest changes in the library or are interested in contributing. However, the *latest* version may not be stable. Feel free to open an [issue](https://github.com/huggingface/transformers/issues) if you encounter an error. + +```shell +git clone https://github.com/huggingface/transformers.git +cd transformers + +# pip +pip install '.[torch]' + +# uv +uv pip install '.[torch]' +``` + +## Quickstart + +Get started with Transformers right away with the [Pipeline](https://huggingface.co/docs/transformers/pipeline_tutorial) API. The `Pipeline` is a high-level inference class that supports text, audio, vision, and multimodal tasks. It handles preprocessing the input and returns the appropriate output. + +Instantiate a pipeline and specify model to use for text generation. The model is downloaded and cached so you can easily reuse it again. Finally, pass some text to prompt the model. + +```py +from transformers import pipeline + +pipeline = pipeline(task="text-generation", model="Qwen/Qwen2.5-1.5B") +pipeline("the secret to baking a really good cake is ") +[{'generated_text': 'the secret to baking a really good cake is 1) to use the right ingredients and 2) to follow the recipe exactly. the recipe for the cake is as follows: 1 cup of sugar, 1 cup of flour, 1 cup of milk, 1 cup of butter, 1 cup of eggs, 1 cup of chocolate chips. if you want to make 2 cakes, how much sugar do you need? To make 2 cakes, you will need 2 cups of sugar.'}] +``` + +To chat with a model, the usage pattern is the same. The only difference is you need to construct a chat history (the input to `Pipeline`) between you and the system. + +> [!TIP] +> You can also chat with a model directly from the command line, as long as [`transformers serve` is running](https://huggingface.co/docs/transformers/main/en/serving). +> ```shell +> transformers chat Qwen/Qwen2.5-0.5B-Instruct +> ``` + +```py +import torch +from transformers import pipeline + +chat = [ + {"role": "system", "content": "You are a sassy, wise-cracking robot as imagined by Hollywood circa 1986."}, + {"role": "user", "content": "Hey, can you tell me any fun things to do in New York?"} +] + +pipeline = pipeline(task="text-generation", model="meta-llama/Meta-Llama-3-8B-Instruct", dtype=torch.bfloat16, device_map="auto") +response = pipeline(chat, max_new_tokens=512) +print(response[0]["generated_text"][-1]["content"]) +``` + +Expand the examples below to see how `Pipeline` works for different modalities and tasks. + +
+Automatic speech recognition + +```py +from transformers import pipeline + +pipeline = pipeline(task="automatic-speech-recognition", model="openai/whisper-large-v3") +pipeline("https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/mlk.flac") +{'text': ' I have a dream that one day this nation will rise up and live out the true meaning of its creed.'} +``` + +
+ +
+Image classification + +

+ +

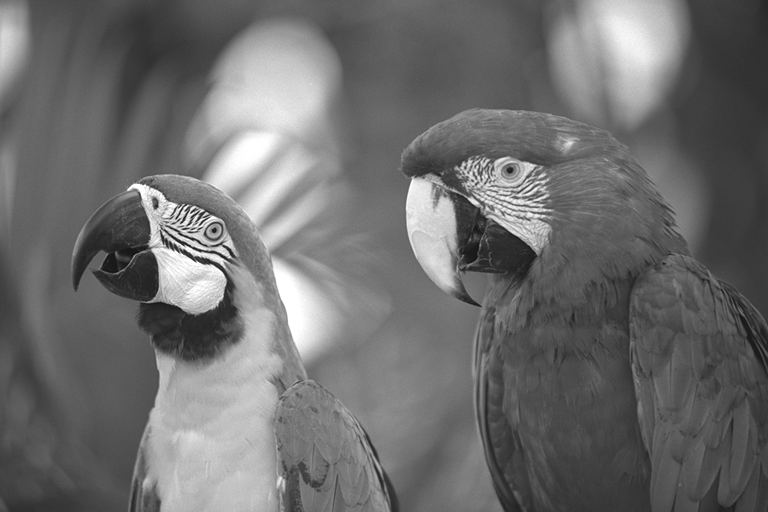
+ +```py +from transformers import pipeline + +pipeline = pipeline(task="image-classification", model="facebook/dinov2-small-imagenet1k-1-layer") +pipeline("https://huggingface.co/datasets/Narsil/image_dummy/raw/main/parrots.png") +[{'label': 'macaw', 'score': 0.997848391532898}, + {'label': 'sulphur-crested cockatoo, Kakatoe galerita, Cacatua galerita', + 'score': 0.0016551691805943847}, + {'label': 'lorikeet', 'score': 0.00018523589824326336}, + {'label': 'African grey, African gray, Psittacus erithacus', + 'score': 7.85409429227002e-05}, + {'label': 'quail', 'score': 5.502637941390276e-05}] +``` + +
+ +
+Visual question answering + +

+ +

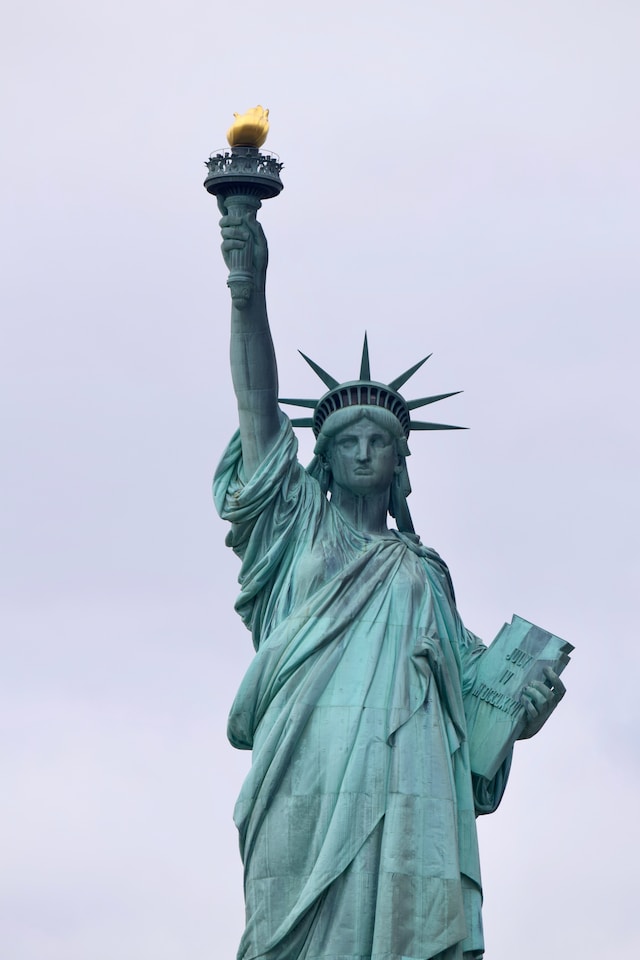
+ +```py +from transformers import pipeline + +pipeline = pipeline(task="visual-question-answering", model="Salesforce/blip-vqa-base") +pipeline( + image="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/tasks/idefics-few-shot.jpg", + question="What is in the image?", +) +[{'answer': 'statue of liberty'}] +``` + +
+ +## Why should I use Transformers? + +1. Easy-to-use state-of-the-art models: + - High performance on natural language understanding & generation, computer vision, audio, video, and multimodal tasks. + - Low barrier to entry for researchers, engineers, and developers. + - Few user-facing abstractions with just three classes to learn. + - A unified API for using all our pretrained models. + +1. Lower compute costs, smaller carbon footprint: + - Share trained models instead of training from scratch. + - Reduce compute time and production costs. + - Dozens of model architectures with 1M+ pretrained checkpoints across all modalities. + +1. Choose the right framework for every part of a model's lifetime: + - Train state-of-the-art models in 3 lines of code. + - Move a single model between PyTorch/JAX/TF2.0 frameworks at will. + - Pick the right framework for training, evaluation, and production. + +1. Easily customize a model or an example to your needs: + - We provide examples for each architecture to reproduce the results published by its original authors. + - Model internals are exposed as consistently as possible. + - Model files can be used independently of the library for quick experiments. + + + Hugging Face Enterprise Hub +
+ +## Why shouldn't I use Transformers? + +- This library is not a modular toolbox of building blocks for neural nets. The code in the model files is not refactored with additional abstractions on purpose, so that researchers can quickly iterate on each of the models without diving into additional abstractions/files. +- The training API is optimized to work with PyTorch models provided by Transformers. For generic machine learning loops, you should use another library like [Accelerate](https://huggingface.co/docs/accelerate). +- The [example scripts](https://github.com/huggingface/transformers/tree/main/examples) are only *examples*. They may not necessarily work out-of-the-box on your specific use case and you'll need to adapt the code for it to work. + +## 100 projects using Transformers + +Transformers is more than a toolkit to use pretrained models, it's a community of projects built around it and the +Hugging Face Hub. We want Transformers to enable developers, researchers, students, professors, engineers, and anyone +else to build their dream projects. + +In order to celebrate Transformers 100,000 stars, we wanted to put the spotlight on the +community with the [awesome-transformers](./awesome-transformers.md) page which lists 100 +incredible projects built with Transformers. + +If you own or use a project that you believe should be part of the list, please open a PR to add it! + +## Example models + +You can test most of our models directly on their [Hub model pages](https://huggingface.co/models). + +Expand each modality below to see a few example models for various use cases. + +
+Audio + +- Audio classification with [CLAP](https://huggingface.co/laion/clap-htsat-fused) +- Automatic speech recognition with [Parakeet](https://huggingface.co/nvidia/parakeet-ctc-1.1b#transcribing-using-transformers-%F0%9F%A4%97), [Whisper](https://huggingface.co/openai/whisper-large-v3-turbo), [GLM-ASR](https://huggingface.co/zai-org/GLM-ASR-Nano-2512) and [Moonshine-Streaming](https://huggingface.co/UsefulSensors/moonshine-streaming-medium) +- Keyword spotting with [Wav2Vec2](https://huggingface.co/superb/wav2vec2-base-superb-ks) +- Speech to speech generation with [Moshi](https://huggingface.co/kyutai/moshiko-pytorch-bf16) +- Text to audio with [MusicGen](https://huggingface.co/facebook/musicgen-large) +- Text to speech with [CSM](https://huggingface.co/sesame/csm-1b) + +
+ +
+Computer vision + +- Automatic mask generation with [SAM](https://huggingface.co/facebook/sam-vit-base) +- Depth estimation with [DepthPro](https://huggingface.co/apple/DepthPro-hf) +- Image classification with [DINO v2](https://huggingface.co/facebook/dinov2-base) +- Keypoint detection with [SuperPoint](https://huggingface.co/magic-leap-community/superpoint) +- Keypoint matching with [SuperGlue](https://huggingface.co/magic-leap-community/superglue_outdoor) +- Object detection with [RT-DETRv2](https://huggingface.co/PekingU/rtdetr_v2_r50vd) +- Pose Estimation with [VitPose](https://huggingface.co/usyd-community/vitpose-base-simple) +- Universal segmentation with [OneFormer](https://huggingface.co/shi-labs/oneformer_ade20k_swin_large) +- Video classification with [VideoMAE](https://huggingface.co/MCG-NJU/videomae-large) + +
+ +
+Multimodal + +- Audio or text to text with [Voxtral](https://huggingface.co/mistralai/Voxtral-Mini-3B-2507), [Audio Flamingo](https://huggingface.co/nvidia/audio-flamingo-3-hf) +- Document question answering with [LayoutLMv3](https://huggingface.co/microsoft/layoutlmv3-base) +- Image or text to text with [Qwen-VL](https://huggingface.co/Qwen/Qwen2.5-VL-3B-Instruct) +- Image captioning [BLIP-2](https://huggingface.co/Salesforce/blip2-opt-2.7b) +- OCR-based document understanding with [GOT-OCR2](https://huggingface.co/stepfun-ai/GOT-OCR-2.0-hf) +- Table question answering with [TAPAS](https://huggingface.co/google/tapas-base) +- Unified multimodal understanding and generation with [Emu3](https://huggingface.co/BAAI/Emu3-Gen) +- Vision to text with [Llava-OneVision](https://huggingface.co/llava-hf/llava-onevision-qwen2-0.5b-ov-hf) +- Visual question answering with [Llava](https://huggingface.co/llava-hf/llava-1.5-7b-hf) +- Visual referring expression segmentation with [Kosmos-2](https://huggingface.co/microsoft/kosmos-2-patch14-224) + +
+ +
+NLP + +- Masked word completion with [ModernBERT](https://huggingface.co/answerdotai/ModernBERT-base) +- Named entity recognition with [Gemma](https://huggingface.co/google/gemma-2-2b) +- Question answering with [Mixtral](https://huggingface.co/mistralai/Mixtral-8x7B-v0.1) +- Summarization with [BART](https://huggingface.co/facebook/bart-large-cnn) +- Translation with [T5](https://huggingface.co/google-t5/t5-base) +- Text generation with [Llama](https://huggingface.co/meta-llama/Llama-3.2-1B) +- Text classification with [Qwen](https://huggingface.co/Qwen/Qwen2.5-0.5B) + +
+ +## Citation + +We now have a [paper](https://www.aclweb.org/anthology/2020.emnlp-demos.6/) you can cite for the 🤗 Transformers library: +```bibtex +@inproceedings{wolf-etal-2020-transformers, + title = "Transformers: State-of-the-Art Natural Language Processing", + author = "Thomas Wolf and Lysandre Debut and Victor Sanh and Julien Chaumond and Clement Delangue and Anthony Moi and Pierric Cistac and Tim Rault and Rémi Louf and Morgan Funtowicz and Joe Davison and Sam Shleifer and Patrick von Platen and Clara Ma and Yacine Jernite and Julien Plu and Canwen Xu and Teven Le Scao and Sylvain Gugger and Mariama Drame and Quentin Lhoest and Alexander M. Rush", + booktitle = "Proceedings of the 2020 Conference on Empirical Methods in Natural Language Processing: System Demonstrations", + month = oct, + year = "2020", + address = "Online", + publisher = "Association for Computational Linguistics", + url = "https://www.aclweb.org/anthology/2020.emnlp-demos.6", + pages = "38--45" +} +``` diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers-5.3.0.dist-info/RECORD b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers-5.3.0.dist-info/RECORD new file mode 100644 index 0000000000000000000000000000000000000000..1e18af6f74ee212b1f81fa2db776fecc6b7fb382 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers-5.3.0.dist-info/RECORD @@ -0,0 +1,4348 @@ +../../../bin/transformers,sha256=A_wU9rBzKIvPKf3yQw5EwMJ27ge2yb2bAXJo3bI_YQk,226 +transformers-5.3.0.dist-info/INSTALLER,sha256=zuuue4knoyJ-UwPPXg8fezS7VCrXJQrAP7zeNuwvFQg,4 +transformers-5.3.0.dist-info/METADATA,sha256=YlnXNp6SgHl-_Vf0Bosd9-LGiN9W83cpJj5IrU_rx_s,32504 +transformers-5.3.0.dist-info/RECORD,, +transformers-5.3.0.dist-info/REQUESTED,sha256=47DEQpj8HBSa-_TImW-5JCeuQeRkm5NMpJWZG3hSuFU,0 +transformers-5.3.0.dist-info/WHEEL,sha256=YCfwYGOYMi5Jhw2fU4yNgwErybb2IX5PEwBKV4ZbdBo,91 +transformers-5.3.0.dist-info/entry_points.txt,sha256=TcBlmquYV475KJBK8EhQNnsLiegWUy_QoKR4R0pMh2g,68 +transformers-5.3.0.dist-info/licenses/LICENSE,sha256=d_1HEN757DwPYiWADgI18VpCWr1KiwNVkSf814JhIEk,11418 +transformers-5.3.0.dist-info/top_level.txt,sha256=GLBaeTo_CSdhnHvbxQ0kzpEHdlLuA_33foIogaWxntI,13 +transformers/__init__.py,sha256=ywwVH2rD2hRDi_jrNc6ruRE8ZAlfYSWL6BfzNvRTbkE,38721 +transformers/__pycache__/__init__.cpython-310.pyc,, +transformers/__pycache__/activations.cpython-310.pyc,, +transformers/__pycache__/audio_utils.cpython-310.pyc,, +transformers/__pycache__/backbone_utils.cpython-310.pyc,, +transformers/__pycache__/cache_utils.cpython-310.pyc,, +transformers/__pycache__/configuration_utils.cpython-310.pyc,, +transformers/__pycache__/conversion_mapping.cpython-310.pyc,, +transformers/__pycache__/convert_slow_tokenizer.cpython-310.pyc,, +transformers/__pycache__/convert_slow_tokenizers_checkpoints_to_fast.cpython-310.pyc,, +transformers/__pycache__/core_model_loading.cpython-310.pyc,, +transformers/__pycache__/debug_utils.cpython-310.pyc,, +transformers/__pycache__/dependency_versions_check.cpython-310.pyc,, +transformers/__pycache__/dependency_versions_table.cpython-310.pyc,, +transformers/__pycache__/dynamic_module_utils.cpython-310.pyc,, +transformers/__pycache__/feature_extraction_sequence_utils.cpython-310.pyc,, +transformers/__pycache__/feature_extraction_utils.cpython-310.pyc,, +transformers/__pycache__/file_utils.cpython-310.pyc,, +transformers/__pycache__/hf_argparser.cpython-310.pyc,, +transformers/__pycache__/hyperparameter_search.cpython-310.pyc,, +transformers/__pycache__/image_processing_base.cpython-310.pyc,, +transformers/__pycache__/image_processing_utils.cpython-310.pyc,, +transformers/__pycache__/image_processing_utils_fast.cpython-310.pyc,, +transformers/__pycache__/image_transforms.cpython-310.pyc,, +transformers/__pycache__/image_utils.cpython-310.pyc,, +transformers/__pycache__/initialization.cpython-310.pyc,, +transformers/__pycache__/masking_utils.cpython-310.pyc,, +transformers/__pycache__/model_debugging_utils.cpython-310.pyc,, +transformers/__pycache__/modelcard.cpython-310.pyc,, +transformers/__pycache__/modeling_attn_mask_utils.cpython-310.pyc,, +transformers/__pycache__/modeling_flash_attention_utils.cpython-310.pyc,, +transformers/__pycache__/modeling_gguf_pytorch_utils.cpython-310.pyc,, +transformers/__pycache__/modeling_layers.cpython-310.pyc,, +transformers/__pycache__/modeling_outputs.cpython-310.pyc,, +transformers/__pycache__/modeling_rope_utils.cpython-310.pyc,, +transformers/__pycache__/modeling_utils.cpython-310.pyc,, +transformers/__pycache__/monkey_patching.cpython-310.pyc,, +transformers/__pycache__/optimization.cpython-310.pyc,, +transformers/__pycache__/processing_utils.cpython-310.pyc,, +transformers/__pycache__/pytorch_utils.cpython-310.pyc,, +transformers/__pycache__/safetensors_conversion.cpython-310.pyc,, +transformers/__pycache__/testing_utils.cpython-310.pyc,, +transformers/__pycache__/time_series_utils.cpython-310.pyc,, +transformers/__pycache__/tokenization_mistral_common.cpython-310.pyc,, +transformers/__pycache__/tokenization_python.cpython-310.pyc,, +transformers/__pycache__/tokenization_utils_base.cpython-310.pyc,, +transformers/__pycache__/tokenization_utils_sentencepiece.cpython-310.pyc,, +transformers/__pycache__/tokenization_utils_tokenizers.cpython-310.pyc,, +transformers/__pycache__/trainer.cpython-310.pyc,, +transformers/__pycache__/trainer_callback.cpython-310.pyc,, +transformers/__pycache__/trainer_jit_checkpoint.cpython-310.pyc,, +transformers/__pycache__/trainer_optimizer.cpython-310.pyc,, +transformers/__pycache__/trainer_pt_utils.cpython-310.pyc,, +transformers/__pycache__/trainer_seq2seq.cpython-310.pyc,, +transformers/__pycache__/trainer_utils.cpython-310.pyc,, +transformers/__pycache__/training_args.cpython-310.pyc,, +transformers/__pycache__/training_args_seq2seq.cpython-310.pyc,, +transformers/__pycache__/video_processing_utils.cpython-310.pyc,, +transformers/__pycache__/video_utils.cpython-310.pyc,, +transformers/activations.py,sha256=EKXLSC-FTF06--W7Heq18U_yHIANCKOLEChTi54fOGc,13176 +transformers/audio_utils.py,sha256=HtLgV6nkfqJjhxYYX180Ugprt2sjyJETRftJLgtq1hA,54555 +transformers/backbone_utils.py,sha256=BQY9JzEZQ37iA_QKOWxOabbg4L628jAVKXhMxsRpjqY,15266 +transformers/cache_utils.py,sha256=5P4gyh7rF-oM5-YtHb0Nbqsy5wcgRPKTYSQDuODEd_0,60147 +transformers/cli/__init__.py,sha256=A4zmzuHD2OHjQ5zmdfcnsj0JeCzHVPtpzh-wCjInugA,606 +transformers/cli/__pycache__/__init__.cpython-310.pyc,, +transformers/cli/__pycache__/add_fast_image_processor.cpython-310.pyc,, +transformers/cli/__pycache__/add_new_model_like.cpython-310.pyc,, +transformers/cli/__pycache__/chat.cpython-310.pyc,, +transformers/cli/__pycache__/download.cpython-310.pyc,, +transformers/cli/__pycache__/serve.cpython-310.pyc,, +transformers/cli/__pycache__/system.cpython-310.pyc,, +transformers/cli/__pycache__/transformers.cpython-310.pyc,, +transformers/cli/add_fast_image_processor.py,sha256=G4tcJrarc3ajPML4rLiBBjiY4Xp4_wcqG_emkJ-Bot4,23296 +transformers/cli/add_new_model_like.py,sha256=mUGL-AajBXUnZkYraoj570MWGHa_e0D7I7U5-ckkUco,33031 +transformers/cli/chat.py,sha256=PwHvO0OaWVN5TqVRFsEDp-D1T6R8Jba7JtBvPKvJciY,24695 +transformers/cli/download.py,sha256=hO2NipXmWif_xNAR0c4CPvZUnxPzfHxBmOu8s2dfTuE,1692 +transformers/cli/serve.py,sha256=5nnDTFj54mn4M4bfcAU-t7bbpaDbvhVRo-_JdP9Jc14,80252 +transformers/cli/system.py,sha256=BqPPxBLFzNjKjfCv3AklfqnVVKyQ04NigSx8HlpDxso,4738 +transformers/cli/transformers.py,sha256=nSgHO3PAGkufNbOI8funjzT36Lb3QR7lUuchJfXa5M4,1367 +transformers/configuration_utils.py,sha256=DbAE6QSuLUtRhb47WwVzS2k90kFPYEb1mOmOAjjaDC8,58130 +transformers/conversion_mapping.py,sha256=y6JM4LbbUFFO9RN1-9YRkaRcCynwlFwVHDnZ2GzKzOQ,21541 +transformers/convert_slow_tokenizer.py,sha256=J8sNKeHC-y9BiwRA35qrrj0fv9j5K3WFWp8zH_9d5pI,77321 +transformers/convert_slow_tokenizers_checkpoints_to_fast.py,sha256=clQ6w0W8vfL_CrRDpPBO4CGXAxAG4AJ9pb8YL5MPhpA,5790 +transformers/core_model_loading.py,sha256=s0Rs8lwKHBUS72o7iT7G7bMd4AAdT8Ef3M6BTTuo6JI,57745 +transformers/data/__init__.py,sha256=MuXSchTzRSaUtUDC1uSeDkHiSbjtrQZg4IoKeKHoH6A,1490 +transformers/data/__pycache__/__init__.cpython-310.pyc,, +transformers/data/__pycache__/data_collator.cpython-310.pyc,, +transformers/data/data_collator.py,sha256=TvK95b5THl-zQUsi4_ST9i_UbuezVEjgXXUlF5ysF6w,69690 +transformers/data/datasets/__init__.py,sha256=_KGvq0E6uO2iT0Kzl_HDJIuz9xkQmePGgfqkRU4hvS8,724 +transformers/data/datasets/__pycache__/__init__.cpython-310.pyc,, +transformers/data/datasets/__pycache__/glue.cpython-310.pyc,, +transformers/data/datasets/__pycache__/squad.cpython-310.pyc,, +transformers/data/datasets/glue.py,sha256=4LZJgtGm27re7foc6KOZ2rAZB3PoCS10JsQ-sbumIBo,6086 +transformers/data/datasets/squad.py,sha256=VaZNZ2SyyZbgOFg-hqnkeI0atrgNIQw5XBYPeYXp4MI,9145 +transformers/data/metrics/__init__.py,sha256=km9yg-ht5wbJYlaeBkJskzapjfpiv9wPArDP_5k4DQw,3640 +transformers/data/metrics/__pycache__/__init__.cpython-310.pyc,, +transformers/data/metrics/__pycache__/squad_metrics.cpython-310.pyc,, +transformers/data/metrics/squad_metrics.py,sha256=__cjdPU1qt3bjnXq3k6CC2_p_5DxbU8p6I5EL40unrg,29685 +transformers/data/processors/__init__.py,sha256=lvN5mp9mdrr5v6QvZT6VcoZ78zZUvXiumTm6Gdvlgvo,1014 +transformers/data/processors/__pycache__/__init__.cpython-310.pyc,, +transformers/data/processors/__pycache__/glue.cpython-310.pyc,, +transformers/data/processors/__pycache__/squad.cpython-310.pyc,, +transformers/data/processors/__pycache__/utils.cpython-310.pyc,, +transformers/data/processors/__pycache__/xnli.cpython-310.pyc,, +transformers/data/processors/glue.py,sha256=e-TbSIQFJ29WhxnS1rn-Ne61Tf322Eh9HzKyZR2c95U,21368 +transformers/data/processors/squad.py,sha256=t7BnHz6ePs3TYfUJA4MekR84fQjw7ocR6HbCVyQyLBE,28895 +transformers/data/processors/utils.py,sha256=IEiGb4u5z80mOFaFUnRVkkk7lT-l19UllT05FUYBxVo,12829 +transformers/data/processors/xnli.py,sha256=6E-hvbeM2Gn_cKCqwB5eq1zHXDRitDTgam6prnfC-KE,3466 +transformers/debug_utils.py,sha256=By3zizwqZFiYRc8hCY3d0bt8qObCjIErVuJK1xJEGro,12964 +transformers/dependency_versions_check.py,sha256=Uj3M5Rn38MDjLg5q9DAz2TGnOdvkdDpwrSrxGjVukQM,2099 +transformers/dependency_versions_table.py,sha256=848_ctrsG6DeEuIAM8wf5XwOOpShcpIvWPS2d3XSn_A,3260 +transformers/distributed/__init__.py,sha256=ds-xiU6Hko8BN-XiIF2cJZPCjrQ-JFlodRARkPK8g-0,978 +transformers/distributed/__pycache__/__init__.cpython-310.pyc,, +transformers/distributed/__pycache__/configuration_utils.cpython-310.pyc,, +transformers/distributed/configuration_utils.py,sha256=c43IoxSKL3FnA9q3-suCYgoMyjfJnLQr5HASppruVTQ,4386 +transformers/dynamic_module_utils.py,sha256=v335cmxljt_a5SCERIgDe3FLzfauGeYZYcTYRlTv3rg,34752 +transformers/feature_extraction_sequence_utils.py,sha256=RoNp3S-PKE_uwUuFivsJXv03Y6-C1X0PRzjtp7UvaOU,18846 +transformers/feature_extraction_utils.py,sha256=F5qOivmPnVPSQJDgEAeD2f5KMQHxXj7fMrJW7cwHLMM,30132 +transformers/file_utils.py,sha256=csjz46-BAJ-tNyLjRAqBQWxZZWCVrRGOoAvDTxgyHSs,2935 +transformers/generation/__init__.py,sha256=ybSh7NZJ4KzeQ_qSGefwE2tDTR86sFHHewnuxMRmQtA,6830 +transformers/generation/__pycache__/__init__.cpython-310.pyc,, +transformers/generation/__pycache__/candidate_generator.cpython-310.pyc,, +transformers/generation/__pycache__/configuration_utils.cpython-310.pyc,, +transformers/generation/__pycache__/logits_process.cpython-310.pyc,, +transformers/generation/__pycache__/stopping_criteria.cpython-310.pyc,, +transformers/generation/__pycache__/streamers.cpython-310.pyc,, +transformers/generation/__pycache__/utils.cpython-310.pyc,, +transformers/generation/__pycache__/watermarking.cpython-310.pyc,, +transformers/generation/candidate_generator.py,sha256=THHwkgZYUtV2LpLB5aIsMc2JkOrWJR4EpYZcGsznYdI,65530 +transformers/generation/configuration_utils.py,sha256=e1UxESjQHEb3h9NadiLOC5nnpu2fa1VzmDqzQCKLHtE,78961 +transformers/generation/continuous_batching/__init__.py,sha256=X3bo8vwLZ3HgUL0z5KAnoyEFQb1VhLwf0nKAyVr-RWs,1027 +transformers/generation/continuous_batching/__pycache__/__init__.cpython-310.pyc,, +transformers/generation/continuous_batching/__pycache__/cache.cpython-310.pyc,, +transformers/generation/continuous_batching/__pycache__/cache_manager.cpython-310.pyc,, +transformers/generation/continuous_batching/__pycache__/continuous_api.cpython-310.pyc,, +transformers/generation/continuous_batching/__pycache__/input_outputs.cpython-310.pyc,, +transformers/generation/continuous_batching/__pycache__/requests.cpython-310.pyc,, +transformers/generation/continuous_batching/__pycache__/scheduler.cpython-310.pyc,, +transformers/generation/continuous_batching/__pycache__/utils.cpython-310.pyc,, +transformers/generation/continuous_batching/cache.py,sha256=1o5oBrrxpWcR4Z54xAJxznRx9kXQ2KJ682gIWQ6Gg9o,39114 +transformers/generation/continuous_batching/cache_manager.py,sha256=OsZ0rEz3tJoqOf2P1Uc7wToQYdCTDTOUJVOJQRSbxfs,26971 +transformers/generation/continuous_batching/continuous_api.py,sha256=t6sl7pnc6TjhzxkiCMb9O3iauwjonkiEl_RhmXp_o40,53079 +transformers/generation/continuous_batching/input_outputs.py,sha256=mGNl-TM__WK2shXdCOyZHGcCP7PIIaRQN40RPZe3V3E,34726 +transformers/generation/continuous_batching/requests.py,sha256=4tOtTz0BPGLSH36PSIoGWZkLnmfHfi4FwlwGrRWXAbE,14622 +transformers/generation/continuous_batching/scheduler.py,sha256=A6OiYOAvPvAVSHWMDzJ6awZ78YgsJDTaBreUvMCxrvA,19610 +transformers/generation/continuous_batching/utils.py,sha256=xN0tpSAHOhNHqtHdMEilAvER1P22ytnrqTA8ojy_PUs,5877 +transformers/generation/logits_process.py,sha256=7Z_XS1sjJEP8NmNJIsh9IF8mbfAslBShfcDRmYOnwm4,149987 +transformers/generation/stopping_criteria.py,sha256=UbIHEmi0BGOVoYOQH-jjZrykGfFA-nqI0xUAxcoy54M,28818 +transformers/generation/streamers.py,sha256=qVM28Z9ELIm4rdI_FsjE2bYzQtvLHLScblTGUoU3SlQ,12970 +transformers/generation/utils.py,sha256=nySPtRsDpB8H-EG_7t1lyilq_WioNuSAhfZq2nwpIVo,211223 +transformers/generation/watermarking.py,sha256=rgkr5v3JeYcNOERGB_qyUQAeiKnvCfB0jRvnK53aLws,24565 +transformers/hf_argparser.py,sha256=dJktlWax22pHlUhCaXiAgNuCTGfGvZXpBB_-tWBRfRA,19734 +transformers/hyperparameter_search.py,sha256=kfMEB-nYTBT2stCzMWeAPvsleR7eI7SJKiIJu3jx1gU,3684 +transformers/image_processing_base.py,sha256=qkCorOUtwCKyXmaNJuMbF3Lo_VJqCb6sPLCgEEYNVqQ,23122 +transformers/image_processing_utils.py,sha256=i7QTWl6JD-aPvbJ8gQ0qRLGdwU0W96G4rLLWpJKCPCM,13746 +transformers/image_processing_utils_fast.py,sha256=aPJLHkv60jNaFPKLNqcifYZLfMIKHftb3EDea_Wl8DQ,38000 +transformers/image_transforms.py,sha256=DxKckrVmeF3lIuWQyMwzEfiAA42IKCdMZxS1denkjwQ,43982 +transformers/image_utils.py,sha256=OmaKT_WPfhaF4T30mzaZD3FGsA6UKk_TeEUBQ4hRByA,37242 +transformers/initialization.py,sha256=WJk05fQ-YuotiSP1w4oLkX2MjBN39BbFofFbiXfw7PE,10979 +transformers/integrations/__init__.py,sha256=vBffUYAuVau5hClI-6nm4GCVsJFupIJVhvBmu-p0eoA,9807 +transformers/integrations/__pycache__/__init__.cpython-310.pyc,, +transformers/integrations/__pycache__/accelerate.cpython-310.pyc,, +transformers/integrations/__pycache__/aqlm.cpython-310.pyc,, +transformers/integrations/__pycache__/awq.cpython-310.pyc,, +transformers/integrations/__pycache__/bitnet.cpython-310.pyc,, +transformers/integrations/__pycache__/bitsandbytes.cpython-310.pyc,, +transformers/integrations/__pycache__/deepspeed.cpython-310.pyc,, +transformers/integrations/__pycache__/eager_paged.cpython-310.pyc,, +transformers/integrations/__pycache__/eetq.cpython-310.pyc,, +transformers/integrations/__pycache__/executorch.cpython-310.pyc,, +transformers/integrations/__pycache__/fbgemm_fp8.cpython-310.pyc,, +transformers/integrations/__pycache__/finegrained_fp8.cpython-310.pyc,, +transformers/integrations/__pycache__/flash_attention.cpython-310.pyc,, +transformers/integrations/__pycache__/flash_paged.cpython-310.pyc,, +transformers/integrations/__pycache__/flex_attention.cpython-310.pyc,, +transformers/integrations/__pycache__/fouroversix.cpython-310.pyc,, +transformers/integrations/__pycache__/fp_quant.cpython-310.pyc,, +transformers/integrations/__pycache__/fsdp.cpython-310.pyc,, +transformers/integrations/__pycache__/ggml.cpython-310.pyc,, +transformers/integrations/__pycache__/higgs.cpython-310.pyc,, +transformers/integrations/__pycache__/hqq.cpython-310.pyc,, +transformers/integrations/__pycache__/hub_kernels.cpython-310.pyc,, +transformers/integrations/__pycache__/integration_utils.cpython-310.pyc,, +transformers/integrations/__pycache__/liger.cpython-310.pyc,, +transformers/integrations/__pycache__/metal_quantization.cpython-310.pyc,, +transformers/integrations/__pycache__/mistral.cpython-310.pyc,, +transformers/integrations/__pycache__/moe.cpython-310.pyc,, +transformers/integrations/__pycache__/mxfp4.cpython-310.pyc,, +transformers/integrations/__pycache__/neftune.cpython-310.pyc,, +transformers/integrations/__pycache__/npu_flash_attention.cpython-310.pyc,, +transformers/integrations/__pycache__/peft.cpython-310.pyc,, +transformers/integrations/__pycache__/quanto.cpython-310.pyc,, +transformers/integrations/__pycache__/quark.cpython-310.pyc,, +transformers/integrations/__pycache__/sdpa_attention.cpython-310.pyc,, +transformers/integrations/__pycache__/sdpa_paged.cpython-310.pyc,, +transformers/integrations/__pycache__/sinq.cpython-310.pyc,, +transformers/integrations/__pycache__/spqr.cpython-310.pyc,, +transformers/integrations/__pycache__/tensor_parallel.cpython-310.pyc,, +transformers/integrations/__pycache__/tiktoken.cpython-310.pyc,, +transformers/integrations/__pycache__/torchao.cpython-310.pyc,, +transformers/integrations/__pycache__/tpu.cpython-310.pyc,, +transformers/integrations/__pycache__/vptq.cpython-310.pyc,, +transformers/integrations/accelerate.py,sha256=ZUYWuXu5YFcDVUDdJXUf0_9T4gWKwlD0wMzGoTzfceY,40368 +transformers/integrations/aqlm.py,sha256=EDEKYoQvw6dF685rU68LtCqv6UuzcydP7rk3Dk7nZIY,3013 +transformers/integrations/awq.py,sha256=YJNs6ZJpE0u8lc70tvUZCZDcw68u83mKYuPE5iry618,4891 +transformers/integrations/bitnet.py,sha256=CPnBKBLOS427NnaISR6YJPnbupmjQ1-9uuvKey-yK0I,14771 +transformers/integrations/bitsandbytes.py,sha256=QvaBP9yi6WFmLWS8P0e7YKNfIh0jtoRS_Nxhp-p7EyY,14469 +transformers/integrations/deepspeed.py,sha256=dxFZkD2Zo9rrG09M6pc0yWpfGs-r7WAaFiITjIjW1PQ,32527 +transformers/integrations/eager_paged.py,sha256=HlcqmSZtvwHzyPtWzO0NeDiy66yZRJVnvoD5ZkQOXAE,3334 +transformers/integrations/eetq.py,sha256=x-zrfBIlJkwJwkNMtHlWmXHZwAtjIwkC6TYIz8Vldok,4849 +transformers/integrations/executorch.py,sha256=gp1hOkfFgjuYudIvCeGkxyj3ulia5aMCMy2LQtmkq1w,46116 +transformers/integrations/fbgemm_fp8.py,sha256=0kBij-u186qgeNfDqfXH-ZEZnzp1FRbeEQsEFPtD3Pg,14280 +transformers/integrations/finegrained_fp8.py,sha256=DsShgt46ptSmtsyBhkPqDDac2vXbRhYfIeJQznIZmx0,34456 +transformers/integrations/flash_attention.py,sha256=HfEll3ptkLhI0qBp8imhEwo9xcLxpdTyG9LnQY9eDfM,3225 +transformers/integrations/flash_paged.py,sha256=eXhytN8pnAjsBGw6-mueDVG5aWLtrdovv1hdadSg4ck,3581 +transformers/integrations/flex_attention.py,sha256=npRY3utTDWP3KKIy3GmZupgE70S388Oa8trKICCXCy8,13331 +transformers/integrations/fouroversix.py,sha256=lYVqBDZH-YR94DvXre9znKmmPkqW8jDfs0Z8nyo0oLw,2845 +transformers/integrations/fp_quant.py,sha256=YxMIY6w_Gp-uAp7zUmIOMNbTQpe5-WPiEF9c1SFVvFs,5712 +transformers/integrations/fsdp.py,sha256=yd1PIBt4d4LlaoV96JWrYEOc0wivcyHfFjozUc-QZgw,3021 +transformers/integrations/ggml.py,sha256=7plilF9IQ7bSc683OjGolUGwqe5ADhbE9XttnC441y8,30843 +transformers/integrations/higgs.py,sha256=sCuXXEolpskQAMq26cfet8jivD0xo4rabunGux7jVDU,30612 +transformers/integrations/hqq.py,sha256=GeTogGSqPyrgTvTHzxwt5TZhpc1vRj_lb2DdWy5BKkI,5075 +transformers/integrations/hub_kernels.py,sha256=PxIVEjr88qf_re0tH3QA93iCMobHf4o-ROH3lEX5ZvQ,18260 +transformers/integrations/integration_utils.py,sha256=Yb4p6EYuLanMNDWGi9qLkJ1brzTcKq6bw6bYN5d50hs,106216 +transformers/integrations/liger.py,sha256=zDMJmGnYHUcZxlLIgKOfjg7RavF_nSCM6qvJxD7cZMk,2012 +transformers/integrations/metal_quantization.py,sha256=686RxJcaL_kRYfjB6U3kE0orOeBP0t_Nc0hCuAcGJ6M,10408 +transformers/integrations/mistral.py,sha256=dIlmD952S101yuAW7xVlDkZkRJzNxRqpjGPprMEZ_ro,4714 +transformers/integrations/moe.py,sha256=coJuvrEzFm6E-fy7jVasyVA2xp_KDUKG8L0pSvNNSz8,22664 +transformers/integrations/mxfp4.py,sha256=cLS91EwlSmnJZCgkhRSGWngQA_hfcOEWDOypQXGByDc,28231 +transformers/integrations/neftune.py,sha256=1YyICbg6VsIQEnzdBcj3tLUXozmjBufVHf00DsLEoGQ,4352 +transformers/integrations/npu_flash_attention.py,sha256=5YBiW6jSW1dlYP-0dLfQJ0XFcX5zqLRUS6qRlESf5s4,4189 +transformers/integrations/peft.py,sha256=gwCSgk9dLGonIfig6XFSgC1Ypr-xygqq4sHeCvYiXV8,47409 +transformers/integrations/quanto.py,sha256=6hTEepeftmrV6M9tmkcp66CZxLgUNo8Ac0gCBqg-XCs,4878 +transformers/integrations/quark.py,sha256=XyOw_pR_3lOkTqSMPW4JWXb2KV2cN5U4i4WOLxL8ayo,2236 +transformers/integrations/sdpa_attention.py,sha256=h_kz0aLYUI31ctpcB0jGskwi_ytiV5aUmVfc2GzFdWQ,4851 +transformers/integrations/sdpa_paged.py,sha256=BBovk8Q4tDw2AQVyUXl4dqXbIyBsLesXXQ5bCWoMdo0,2421 +transformers/integrations/sinq.py,sha256=QHZhvyMzX-2EPpXK7ircYMG0BUd1LQCfDgvfdSrR8Lo,5581 +transformers/integrations/spqr.py,sha256=YPuXOC0FfS5RFYsJ9JbxhAUs3xDKTToMBLvoSxQxKZU,3306 +transformers/integrations/tensor_parallel.py,sha256=1jBULDsqgCn_ZwPlsfooeKjDJbSyhiSZ3gFnY_iMQaw,62562 +transformers/integrations/tiktoken.py,sha256=G3tVAsANX0WyvDx4aNKarPB7l9RNhJ1ghvI7i5cp3qQ,1993 +transformers/integrations/torchao.py,sha256=VGEgIZLC3ddXscmAkCjXI3LVMjZ68l4dphG9ObZ5_qo,13077 +transformers/integrations/tpu.py,sha256=9mL_kSiV1hSj6RMCzllIO1sI54E-G9omWqxCTOXdP-A,9736 +transformers/integrations/vptq.py,sha256=5VngTj5ip6JdWAFgfXY4YdFsaoRpegGzZd8S5zHheVY,3623 +transformers/loss/__init__.py,sha256=qETsqCwayu6Ymj_J4_A_eiwiaMRHQ0noWKM35naanzc,606 +transformers/loss/__pycache__/__init__.cpython-310.pyc,, +transformers/loss/__pycache__/loss_d_fine.cpython-310.pyc,, +transformers/loss/__pycache__/loss_deformable_detr.cpython-310.pyc,, +transformers/loss/__pycache__/loss_for_object_detection.cpython-310.pyc,, +transformers/loss/__pycache__/loss_grounding_dino.cpython-310.pyc,, +transformers/loss/__pycache__/loss_lw_detr.cpython-310.pyc,, +transformers/loss/__pycache__/loss_rt_detr.cpython-310.pyc,, +transformers/loss/__pycache__/loss_utils.cpython-310.pyc,, +transformers/loss/loss_d_fine.py,sha256=YdS9uLVALctyEBpvI1Zzxv2MxcwvBlSx7qIPfJA4wrA,15466 +transformers/loss/loss_deformable_detr.py,sha256=e9Jc3K5fIygR9xO1kQm1_8FQhVw2GfhkmtaV2SHEbZ0,8134 +transformers/loss/loss_for_object_detection.py,sha256=i68qif_xh3i4nzqMqMoRjRYMPpQb_AMhuXK5UORb9P4,24347 +transformers/loss/loss_grounding_dino.py,sha256=RZZzjQgZPbLi89rq1iBYBhhzDx89orv4hY03NcVe7TA,12003 +transformers/loss/loss_lw_detr.py,sha256=B8CTgSpwwAu2QLM8_538PfgMo8ezBgQ6Vj2MGqhYV2k,15379 +transformers/loss/loss_rt_detr.py,sha256=94p5gMIdF5hTMFeylN-AQ-W5mH6VOo-l_DJvGKP8hsc,21952 +transformers/loss/loss_utils.py,sha256=PfNDjwy4DLe5A9bQb1IoOXVvTKkwGgLXk3SK4JnCfZ8,7061 +transformers/masking_utils.py,sha256=w8gve3tuA9PwS6bGxYo91pEGI2NkUuxn73Dj61Ivn-c,74373 +transformers/model_debugging_utils.py,sha256=4ug0HoBDCE0o9gq10ghjFNrq2k4D0cjGtO30IlDLGEQ,17044 +transformers/modelcard.py,sha256=12D2CCJ0tH6kT9FgT2yHwxwmXZ4VOOSRD3X592VDZ7o,22230 +transformers/modeling_attn_mask_utils.py,sha256=ebFVViMLxu8-v6UMU-jd-RwVhyAt2WX0nHlRmnMG0F8,21843 +transformers/modeling_flash_attention_utils.py,sha256=LFuDnOrimKfZlfK4rojMX4FR7gCo3czO7RvjvR75u3I,31910 +transformers/modeling_gguf_pytorch_utils.py,sha256=SsigKAA9xJJWBEwJcn7v0Lkrh4fWHgevuq-bMdHLf8I,24799 +transformers/modeling_layers.py,sha256=nkcmwHz8iV2V-adbDn0juFYVdQgIEWlecPqHmwoY2uQ,11476 +transformers/modeling_outputs.py,sha256=uyFra5xLPWnydzZ7NxHF80yOQtf5jgo5MKZNEHRl9_A,108678 +transformers/modeling_rope_utils.py,sha256=FEB9Ol-ybC4Up1phlYh-Fj8x-_MH2HDbsDAxvJ8BLs0,52967 +transformers/modeling_utils.py,sha256=cH-SckTMj-Kz6aicL8J2luO-sIhStT7z22n60UdRXxM,251060 +transformers/models/__init__.py,sha256=bZeZ1j-Pq8q7SVRZhohnx25dCrWEIQY4ge5Q0FPVRFo,13152 +transformers/models/__pycache__/__init__.cpython-310.pyc,, +transformers/models/afmoe/__init__.py,sha256=6JBjMRMPG1r9Ivg3wbHIKDaEdBKfqmhPYLJOLz2ZCz0,1009 +transformers/models/afmoe/__pycache__/__init__.cpython-310.pyc,, +transformers/models/afmoe/__pycache__/configuration_afmoe.cpython-310.pyc,, +transformers/models/afmoe/__pycache__/modeling_afmoe.cpython-310.pyc,, +transformers/models/afmoe/__pycache__/modular_afmoe.cpython-310.pyc,, +transformers/models/afmoe/configuration_afmoe.py,sha256=R_WB8Hd5WH9K93gLWcHXPyNTry5852dtTin60NFLBkg,10837 +transformers/models/afmoe/modeling_afmoe.py,sha256=aVzrkpuXfeE_707wr4uMjzRmHkTPG8lvojajXWCePPI,30213 +transformers/models/afmoe/modular_afmoe.py,sha256=ErdPG_6Lt89V1wNh_CC7DMOolIlIROh3wgg0IJGSado,18202 +transformers/models/aimv2/__init__.py,sha256=cDli19QT_YABtn4DPLYfoWHtkmOQYGipAgPKGuRje4c,991 +transformers/models/aimv2/__pycache__/__init__.cpython-310.pyc,, +transformers/models/aimv2/__pycache__/configuration_aimv2.cpython-310.pyc,, +transformers/models/aimv2/__pycache__/modeling_aimv2.cpython-310.pyc,, +transformers/models/aimv2/__pycache__/modular_aimv2.cpython-310.pyc,, +transformers/models/aimv2/configuration_aimv2.py,sha256=fu3f4349RxTIZcDSCOBc5TfzInbgaeyeh2n4wGc9mVM,13520 +transformers/models/aimv2/modeling_aimv2.py,sha256=uatT1mdp5dAAKO82CnHaO2LcM-4sOo1oZeH8DNsyjj0,29242 +transformers/models/aimv2/modular_aimv2.py,sha256=5K1Rud3H2YJYML3rm_zb3RXnZdMu2bqyBCM1ak5AXU8,28257 +transformers/models/albert/__init__.py,sha256=hxvpETbDcdrI03UPZb4pTpVbADWISlvpVvoMw-x67mY,1032 +transformers/models/albert/__pycache__/__init__.cpython-310.pyc,, +transformers/models/albert/__pycache__/configuration_albert.cpython-310.pyc,, +transformers/models/albert/__pycache__/modeling_albert.cpython-310.pyc,, +transformers/models/albert/__pycache__/tokenization_albert.cpython-310.pyc,, +transformers/models/albert/configuration_albert.py,sha256=L9xH9yGFEQfZs5vd6swOIcbQ6YlZY5QgQcZzOgqtxuw,6845 +transformers/models/albert/modeling_albert.py,sha256=ecze7TR0M32wX33HV9mjyApM8kZKdZUP3YaxqufFnec,38577 +transformers/models/albert/tokenization_albert.py,sha256=_V2aLl8NT0jldwOocNmjC4G9svDD7UVN6B5Z6ZbfJo8,7737 +transformers/models/align/__init__.py,sha256=QqTKk-Z4BylY6EkBSlYvKXVhT2te-m2Al626OUAz-r4,1027 +transformers/models/align/__pycache__/__init__.cpython-310.pyc,, +transformers/models/align/__pycache__/configuration_align.cpython-310.pyc,, +transformers/models/align/__pycache__/modeling_align.cpython-310.pyc,, +transformers/models/align/__pycache__/processing_align.cpython-310.pyc,, +transformers/models/align/configuration_align.py,sha256=RpkRggefCJgUdhophYdbMEsEFpcbKY4uL2_xvOs3Yq8,15449 +transformers/models/align/modeling_align.py,sha256=eaG1YnpKF_SyilYXDLiu3b7QAC_qhar-1cqp3uno0q0,48828 +transformers/models/align/processing_align.py,sha256=oUDbKwqG-ts86VV2V5tY0PbIfGIW1hiBwnkU1j8ljPg,1237 +transformers/models/altclip/__init__.py,sha256=405IijUCYr1EGvOqg1xzds_GHOlxCl0HCsf1rI0wtPY,1033 +transformers/models/altclip/__pycache__/__init__.cpython-310.pyc,, +transformers/models/altclip/__pycache__/configuration_altclip.cpython-310.pyc,, +transformers/models/altclip/__pycache__/modeling_altclip.cpython-310.pyc,, +transformers/models/altclip/__pycache__/processing_altclip.cpython-310.pyc,, +transformers/models/altclip/configuration_altclip.py,sha256=0Z9gcS6LNWjbOszuJpIcEfqHOrbSsgIyDnw1v-WD-Bg,17672 +transformers/models/altclip/modeling_altclip.py,sha256=jIzihduJ2rdOvin0xur0xSNZpf5gO8kwT5b_SJhRsvo,54918 +transformers/models/altclip/processing_altclip.py,sha256=tyodo5ptS2sggwrFhAJMWjlia7qrYPNDDeJc4y5mnaY,1000 +transformers/models/apertus/__init__.py,sha256=GthOdmsWx7l04JZ0ucrJtn6ayZzaHRgujOMGUbGdtvY,1256 +transformers/models/apertus/__pycache__/__init__.cpython-310.pyc,, +transformers/models/apertus/__pycache__/configuration_apertus.cpython-310.pyc,, +transformers/models/apertus/__pycache__/modeling_apertus.cpython-310.pyc,, +transformers/models/apertus/__pycache__/modular_apertus.cpython-310.pyc,, +transformers/models/apertus/configuration_apertus.py,sha256=3YRVRvGiqmIbJUwItRjrWGvhlTowKGwSWdeAFsDsDN4,8902 +transformers/models/apertus/modeling_apertus.py,sha256=Yr5tn33QNKzXVvOi4JL4-bHFf5uzgl_ActtaLLkDkg4,22418 +transformers/models/apertus/modular_apertus.py,sha256=8sRb5KarHXXdpubtLC7ECnJK_Cy0UJqjPtXuLWYpSGU,14623 +transformers/models/arcee/__init__.py,sha256=bysIumYEa1Z1bCLBaaP_SCT_6poh8zFLgxt_4Ib-Diw,1009 +transformers/models/arcee/__pycache__/__init__.cpython-310.pyc,, +transformers/models/arcee/__pycache__/configuration_arcee.cpython-310.pyc,, +transformers/models/arcee/__pycache__/modeling_arcee.cpython-310.pyc,, +transformers/models/arcee/__pycache__/modular_arcee.cpython-310.pyc,, +transformers/models/arcee/configuration_arcee.py,sha256=BXeNnUPiVGECUaqWBvQC-bgtrre3JgqRRPum8SIs02I,9096 +transformers/models/arcee/modeling_arcee.py,sha256=XldHBXyg6vNOG5PWxPaFM2j0oG0oPVHkn6W3uC7sGdE,22366 +transformers/models/arcee/modular_arcee.py,sha256=qtSWZn0NfcbQ1o9smgIRwelbl3Fvy8RwRRXatbk3kYA,8866 +transformers/models/aria/__init__.py,sha256=I3vYPjV-sDl0OAILLADGZ7hUkk9ZsmyZ8CEf9tie_dY,1066 +transformers/models/aria/__pycache__/__init__.cpython-310.pyc,, +transformers/models/aria/__pycache__/configuration_aria.cpython-310.pyc,, +transformers/models/aria/__pycache__/image_processing_aria.cpython-310.pyc,, +transformers/models/aria/__pycache__/modeling_aria.cpython-310.pyc,, +transformers/models/aria/__pycache__/modular_aria.cpython-310.pyc,, +transformers/models/aria/__pycache__/processing_aria.cpython-310.pyc,, +transformers/models/aria/configuration_aria.py,sha256=kOiIT6xFVGz1WoB08Z8iNGljukzQMYE8JDMo96I29l0,13316 +transformers/models/aria/image_processing_aria.py,sha256=5WlAr7abi7u95Da30xs-tjx_3y1hA_VJ99XnX4F61dc,24588 +transformers/models/aria/modeling_aria.py,sha256=_JFipCufAwsLdJw0m6ropxuOM1i-WvGuBcL4Hk_BvPo,51338 +transformers/models/aria/modular_aria.py,sha256=2IyEOFWBpWxjJI5hHRKoncmcOUSkmL3Ea9zzwT4dkmk,66124 +transformers/models/aria/processing_aria.py,sha256=AGOLyF1eGFtFIjElzx1RCWjC9dpQhJIGv-rhv7K126Q,8925 +transformers/models/audio_spectrogram_transformer/__init__.py,sha256=a_YVwB1p4_PPeqPFWqFsGSGSQVTaSUXY0xsOd_Gflqs,1107 +transformers/models/audio_spectrogram_transformer/__pycache__/__init__.cpython-310.pyc,, +transformers/models/audio_spectrogram_transformer/__pycache__/configuration_audio_spectrogram_transformer.cpython-310.pyc,, +transformers/models/audio_spectrogram_transformer/__pycache__/feature_extraction_audio_spectrogram_transformer.cpython-310.pyc,, +transformers/models/audio_spectrogram_transformer/__pycache__/modeling_audio_spectrogram_transformer.cpython-310.pyc,, +transformers/models/audio_spectrogram_transformer/configuration_audio_spectrogram_transformer.py,sha256=IfR4TKKLVsbGAI56k7xe9stuB2w_jYAKnA1oLCm640g,5886 +transformers/models/audio_spectrogram_transformer/feature_extraction_audio_spectrogram_transformer.py,sha256=q0lXdJtREwZ0E9zWYtwhKVK5phDSl-i0UV4sqx_x_OQ,9795 +transformers/models/audio_spectrogram_transformer/modeling_audio_spectrogram_transformer.py,sha256=yuwxkI3eIP7X00Fylqzd05Ivx54I0sZtrgWd0tiEOmY,17947 +transformers/models/audioflamingo3/__init__.py,sha256=IIl7s3NZKsVHtQapt7nCGPMbZ2OhlGsgUe8MPeeKgDE,1085 +transformers/models/audioflamingo3/__pycache__/__init__.cpython-310.pyc,, +transformers/models/audioflamingo3/__pycache__/configuration_audioflamingo3.cpython-310.pyc,, +transformers/models/audioflamingo3/__pycache__/modeling_audioflamingo3.cpython-310.pyc,, +transformers/models/audioflamingo3/__pycache__/modular_audioflamingo3.cpython-310.pyc,, +transformers/models/audioflamingo3/__pycache__/processing_audioflamingo3.cpython-310.pyc,, +transformers/models/audioflamingo3/configuration_audioflamingo3.py,sha256=O7ZSXZdZsJwFPCR3LbMoHw0G-lTpkAJsjRlnzXHLRf8,8983 +transformers/models/audioflamingo3/modeling_audioflamingo3.py,sha256=22CjCg16dVu0YFa1Exi04n0xhhV2iDL93iF9RwheLVI,26547 +transformers/models/audioflamingo3/modular_audioflamingo3.py,sha256=9kLY_dvO4lrvzfecQ6yA0QOEwSEfw8HoOwEyZDPXnC4,13096 +transformers/models/audioflamingo3/processing_audioflamingo3.py,sha256=2jKhVlQL2hU7HfDdSxzNZdZbHrL_J_b1cD3ZYIL07fI,13547 +transformers/models/auto/__init__.py,sha256=X1F9TGTiKC60ZRJwdrKDzp1SRadfScfXpM5VqoUrk6M,1218 +transformers/models/auto/__pycache__/__init__.cpython-310.pyc,, +transformers/models/auto/__pycache__/auto_factory.cpython-310.pyc,, +transformers/models/auto/__pycache__/configuration_auto.cpython-310.pyc,, +transformers/models/auto/__pycache__/feature_extraction_auto.cpython-310.pyc,, +transformers/models/auto/__pycache__/image_processing_auto.cpython-310.pyc,, +transformers/models/auto/__pycache__/modeling_auto.cpython-310.pyc,, +transformers/models/auto/__pycache__/processing_auto.cpython-310.pyc,, +transformers/models/auto/__pycache__/tokenization_auto.cpython-310.pyc,, +transformers/models/auto/__pycache__/video_processing_auto.cpython-310.pyc,, +transformers/models/auto/auto_factory.py,sha256=rtd3Vpmt3fhhEVDxf7kRk5dMb3vSeCbv-mJ_-Kul3uM,31452 +transformers/models/auto/configuration_auto.py,sha256=kz86qomlDukcM-AQ2TD4bn-pDvRDUyHJmzsiKso2j4g,60671 +transformers/models/auto/feature_extraction_auto.py,sha256=nl5Q-9bLqApauUOUsm44IJZcDwUUColCS8K5gbhhnhY,19145 +transformers/models/auto/image_processing_auto.py,sha256=cLZmJ0Z2vFM7xWJtDYWersb0IrO2R0e0RbDxaWlioIM,39556 +transformers/models/auto/modeling_auto.py,sha256=cWflWDwzGp7Y7-9uD1ZBBUhYdoScPZec4-NADsjlntk,95694 +transformers/models/auto/processing_auto.py,sha256=9fS88gfVpuUuA-HKvRRYwW7b-VeDUry7HmxQ1w6V7Yc,22134 +transformers/models/auto/tokenization_auto.py,sha256=X0CtRNdtHy1898GVgG4_KkSeErVbVF_K7dNLpOLJhqM,43886 +transformers/models/auto/video_processing_auto.py,sha256=f6OAzLZEzEVmY0afyaHXE4K_f4X4rgbAruuSWejs75w,20607 +transformers/models/autoformer/__init__.py,sha256=EzGIA8hECx9XytdzTifaGyGp7hrXqlyP0slqAq8xBNY,1001 +transformers/models/autoformer/__pycache__/__init__.cpython-310.pyc,, +transformers/models/autoformer/__pycache__/configuration_autoformer.cpython-310.pyc,, +transformers/models/autoformer/__pycache__/modeling_autoformer.cpython-310.pyc,, +transformers/models/autoformer/configuration_autoformer.py,sha256=vPBNEtegp9l-AbyUVGRQ3W1MA9M3d-p0uqJ9J1OLogg,12136 +transformers/models/autoformer/modeling_autoformer.py,sha256=vbKWsFz9X_MP-IQSxiIDC2M_WaGrzaqUKegELNynryM,98538 +transformers/models/aya_vision/__init__.py,sha256=-DIHmMjkXOyNGbMtZJkHtLiOzdxOYSrKq4_mmR09cfk,1042 +transformers/models/aya_vision/__pycache__/__init__.cpython-310.pyc,, +transformers/models/aya_vision/__pycache__/configuration_aya_vision.cpython-310.pyc,, +transformers/models/aya_vision/__pycache__/modeling_aya_vision.cpython-310.pyc,, +transformers/models/aya_vision/__pycache__/modular_aya_vision.cpython-310.pyc,, +transformers/models/aya_vision/__pycache__/processing_aya_vision.cpython-310.pyc,, +transformers/models/aya_vision/configuration_aya_vision.py,sha256=V1zZH5qzEeMkQYcBzLToin17G4kWFv-QuXx4wRx_1IE,4980 +transformers/models/aya_vision/modeling_aya_vision.py,sha256=XtTbLRwdQgtIGSxjiIh0hpssfjuXYzlGHp5XZ9wF5mo,20578 +transformers/models/aya_vision/modular_aya_vision.py,sha256=WB_8An06s3oaXV7nS8xnqyt2mNRdbdEQk_Bk7LPobSM,11385 +transformers/models/aya_vision/processing_aya_vision.py,sha256=PjgsEdgLifbSsIgIrQSh5pxZfTVDFItpzQjyau44rP4,9272 +transformers/models/bamba/__init__.py,sha256=gtebRUrAdiwq-rJmlM5qpbtbGEg-xxA3pjivOHJvaRs,1040 +transformers/models/bamba/__pycache__/__init__.cpython-310.pyc,, +transformers/models/bamba/__pycache__/configuration_bamba.cpython-310.pyc,, +transformers/models/bamba/__pycache__/modeling_bamba.cpython-310.pyc,, +transformers/models/bamba/__pycache__/modular_bamba.cpython-310.pyc,, +transformers/models/bamba/configuration_bamba.py,sha256=QKjEmyJI_91RgKvJ32TuEbd4jFeMGO57UUGjs5NvLNE,11683 +transformers/models/bamba/modeling_bamba.py,sha256=lSlNZee1Hp0_gzreATLqlwBlC4WLe51x0_nsvkd7m7o,64698 +transformers/models/bamba/modular_bamba.py,sha256=k7UGKgJTnfOsn4n-CFpHF3s8Gq_LPyWUQYjW1zj4kuQ,48149 +transformers/models/bark/__init__.py,sha256=fIlOQ6RPBARVhUKdjNx2Nvf09azEI6AiPv3lyWjk0Gc,1024 +transformers/models/bark/__pycache__/__init__.cpython-310.pyc,, +transformers/models/bark/__pycache__/configuration_bark.cpython-310.pyc,, +transformers/models/bark/__pycache__/generation_configuration_bark.cpython-310.pyc,, +transformers/models/bark/__pycache__/modeling_bark.cpython-310.pyc,, +transformers/models/bark/__pycache__/processing_bark.cpython-310.pyc,, +transformers/models/bark/configuration_bark.py,sha256=e2uR82rAtFLU53kS_zRc75y358yXawOthHIa2zXRI-g,11627 +transformers/models/bark/generation_configuration_bark.py,sha256=_aItFYGQo7FpoRIhWqeyleIlazrOhCBnF4HYq5AViCg,14890 +transformers/models/bark/modeling_bark.py,sha256=5eZMQ8WLTHsRHEaqClTWOUCcmlgULNyMsVGVX7Po15A,66893 +transformers/models/bark/processing_bark.py,sha256=S248G60IBsCzKoC8X4XXDK7oYshMaOEY-S192rsHfa4,14097 +transformers/models/bart/__init__.py,sha256=S_TylapQzJgRn1IAHgBjIlpDKOUiRDrWXvXbf-72BQc,1070 +transformers/models/bart/__pycache__/__init__.cpython-310.pyc,, +transformers/models/bart/__pycache__/configuration_bart.cpython-310.pyc,, +transformers/models/bart/__pycache__/modeling_bart.cpython-310.pyc,, +transformers/models/bart/__pycache__/tokenization_bart.cpython-310.pyc,, +transformers/models/bart/configuration_bart.py,sha256=0I4w_MSdSVIhHB4JRa0hFP9vwijAHq7zNF2KJtjByQk,7621 +transformers/models/bart/modeling_bart.py,sha256=ECdSPufad0AOz3lrLlgpQyQkWeRpR7YLpV9Xk2Hexug,71233 +transformers/models/bart/tokenization_bart.py,sha256=DnPB-2ksaq1XKX-4IC6iQ-B5fPUsErQVrDPn_4R7X8A,827 +transformers/models/barthez/__init__.py,sha256=LJe6JwskLg0PCFB6QkvMYXdiQ8ofaLI5NrfeQD0NHGE,958 +transformers/models/barthez/__pycache__/__init__.cpython-310.pyc,, +transformers/models/barthez/__pycache__/tokenization_barthez.cpython-310.pyc,, +transformers/models/barthez/tokenization_barthez.py,sha256=SJ-XLtE6H58H5zU5oJWvtiigDaJs6Uzc9B-5VUIpYIA,6111 +transformers/models/bartpho/__init__.py,sha256=DN0zgU4dM841Kqqo6wN8FpWFeWYHCBxIq3lxrg5vUoU,958 +transformers/models/bartpho/__pycache__/__init__.cpython-310.pyc,, +transformers/models/bartpho/__pycache__/tokenization_bartpho.cpython-310.pyc,, +transformers/models/bartpho/tokenization_bartpho.py,sha256=K6XSQKIJPKdkwmLtnmXzFHfpo-vzamVIYx_nKfHL70c,14255 +transformers/models/beit/__init__.py,sha256=hvsrXPo9G4bktKW3Re5u3DZaDp8GU57HYNKL2firnPg,1119 +transformers/models/beit/__pycache__/__init__.cpython-310.pyc,, +transformers/models/beit/__pycache__/configuration_beit.cpython-310.pyc,, +transformers/models/beit/__pycache__/image_processing_beit.cpython-310.pyc,, +transformers/models/beit/__pycache__/image_processing_beit_fast.cpython-310.pyc,, +transformers/models/beit/__pycache__/modeling_beit.cpython-310.pyc,, +transformers/models/beit/configuration_beit.py,sha256=_6hz8q5d_ajIG0TiwwUvqVAXNj2L4i9_g2GXUc-DmQc,10576 +transformers/models/beit/image_processing_beit.py,sha256=zW704TiUqjLqNYHq87MBwz4eCkX7yYysZ72iDIYPQcQ,23997 +transformers/models/beit/image_processing_beit_fast.py,sha256=otP57DKidDrRyK2qgKWUaAOMWTgCwjZx1l8WNUgmzgM,8257 +transformers/models/beit/modeling_beit.py,sha256=G0s9pJaOw-8ZMz0wM5fQnCVtvz6M82NsBmxqi457NHs,59754 +transformers/models/bert/__init__.py,sha256=8wed5_ySi76CWDslJ4BoPdgV2Yg_TJ0vJjlDgbNKUMo,1026 +transformers/models/bert/__pycache__/__init__.cpython-310.pyc,, +transformers/models/bert/__pycache__/configuration_bert.cpython-310.pyc,, +transformers/models/bert/__pycache__/modeling_bert.cpython-310.pyc,, +transformers/models/bert/__pycache__/tokenization_bert.cpython-310.pyc,, +transformers/models/bert/__pycache__/tokenization_bert_legacy.cpython-310.pyc,, +transformers/models/bert/configuration_bert.py,sha256=O2VLcScpCItezBFvTxUlFUSQ7rPs_2zvW3Lgkw_yKOI,6247 +transformers/models/bert/modeling_bert.py,sha256=hB1KEzsN3UN_ZdKu0RVLJGx17yP4tCDZSoOHf71b64o,57159 +transformers/models/bert/tokenization_bert.py,sha256=_2q3IUx7jtwz4EWFy6_6veCB9TZBofFlDQgDqR740Cg,6075 +transformers/models/bert/tokenization_bert_legacy.py,sha256=ReTGY8HTxwQSPRvp0Q_9EQCmMtXn-RERINT8f7xNin4,19727 +transformers/models/bert_generation/__init__.py,sha256=sLEyyFf2yI6QflP1lTI9LXUF5PvWBvu-fsaFbjund5I,1059 +transformers/models/bert_generation/__pycache__/__init__.cpython-310.pyc,, +transformers/models/bert_generation/__pycache__/configuration_bert_generation.cpython-310.pyc,, +transformers/models/bert_generation/__pycache__/modeling_bert_generation.cpython-310.pyc,, +transformers/models/bert_generation/__pycache__/tokenization_bert_generation.cpython-310.pyc,, +transformers/models/bert_generation/configuration_bert_generation.py,sha256=KXVF97Hzie-ke6bPOwBmaRRMNw3nUuLQkhCbpgcI05k,6384 +transformers/models/bert_generation/modeling_bert_generation.py,sha256=3vLNnsneu9wDePObaaaw0j983ZqO2ek_3WF7XLiX9wM,30717 +transformers/models/bert_generation/tokenization_bert_generation.py,sha256=y8DaWI_h6ETCn27QThQ2ciu2V4JKgEsaXUNgC0QNlNQ,4342 +transformers/models/bert_japanese/__init__.py,sha256=94xfgVPnIQuHQxvmc55_EedJlJQTnHiL4va6Ry6x3LE,964 +transformers/models/bert_japanese/__pycache__/__init__.cpython-310.pyc,, +transformers/models/bert_japanese/__pycache__/tokenization_bert_japanese.cpython-310.pyc,, +transformers/models/bert_japanese/tokenization_bert_japanese.py,sha256=jkBjaGI_BaR33MlOniWhh1PSt3vehied8hXRbS4mYEo,35322 +transformers/models/bertweet/__init__.py,sha256=EZegs0rWTTCiOC_eY-M8eV7bCcwU60dB0HsM1S1VDzQ,959 +transformers/models/bertweet/__pycache__/__init__.cpython-310.pyc,, +transformers/models/bertweet/__pycache__/tokenization_bertweet.cpython-310.pyc,, +transformers/models/bertweet/tokenization_bertweet.py,sha256=2wVAfZKa_0vdlUG-CCVxygWZxrCKS6PAhKJrJqPWJXs,24387 +transformers/models/big_bird/__init__.py,sha256=VAC27mMypSm_-3AEQ179PtQF1Dpq4XNnhs29j6n5KyU,1038 +transformers/models/big_bird/__pycache__/__init__.cpython-310.pyc,, +transformers/models/big_bird/__pycache__/configuration_big_bird.cpython-310.pyc,, +transformers/models/big_bird/__pycache__/modeling_big_bird.cpython-310.pyc,, +transformers/models/big_bird/__pycache__/tokenization_big_bird.cpython-310.pyc,, +transformers/models/big_bird/configuration_big_bird.py,sha256=912eTArz_9yfyO4bBtFyHfTJZKyOFsCFyo_CQQkAX3I,7528 +transformers/models/big_bird/modeling_big_bird.py,sha256=L5l-CVqDLhUCW8SnGyNP5s3ZZRcta0P6BEI16ZbX9uw,119417 +transformers/models/big_bird/tokenization_big_bird.py,sha256=mTVWymvsL_HJ0UYDkF99iVcC_aY4HH2Kku2MJ8u1Mys,7521 +transformers/models/bigbird_pegasus/__init__.py,sha256=7zOl1EhO8W2S9jE0FsyEoW8kV6yn5bLA0dspGFM1mLQ,1011 +transformers/models/bigbird_pegasus/__pycache__/__init__.cpython-310.pyc,, +transformers/models/bigbird_pegasus/__pycache__/configuration_bigbird_pegasus.cpython-310.pyc,, +transformers/models/bigbird_pegasus/__pycache__/modeling_bigbird_pegasus.cpython-310.pyc,, +transformers/models/bigbird_pegasus/configuration_bigbird_pegasus.py,sha256=WnvUs5jElreefBeCvbss1oiLJxtjWD3UVaO2gRLzWs4,8700 +transformers/models/bigbird_pegasus/modeling_bigbird_pegasus.py,sha256=Pel3FRqNgbGKem0YVSqHXfaExFBau6jeZ9AsVzUkFkM,125473 +transformers/models/biogpt/__init__.py,sha256=pZxVjmVzt7FXlkMO_5fMg01eyPvvHYXmDA33MKhp6Yk,1032 +transformers/models/biogpt/__pycache__/__init__.cpython-310.pyc,, +transformers/models/biogpt/__pycache__/configuration_biogpt.cpython-310.pyc,, +transformers/models/biogpt/__pycache__/modeling_biogpt.cpython-310.pyc,, +transformers/models/biogpt/__pycache__/modular_biogpt.cpython-310.pyc,, +transformers/models/biogpt/__pycache__/tokenization_biogpt.cpython-310.pyc,, +transformers/models/biogpt/configuration_biogpt.py,sha256=437iAIL_5evhRIP3siKaVOamCeliBrnta1ZpEHasD4Q,6446 +transformers/models/biogpt/modeling_biogpt.py,sha256=E_xUsseRMDYhl9jv2tJEN7uvtnKVn0ld3JpGC74Vu04,33951 +transformers/models/biogpt/modular_biogpt.py,sha256=ErcsPOA-bTShFi00z-tnzHr2y8cYxFErjRhaekWmBEs,25503 +transformers/models/biogpt/tokenization_biogpt.py,sha256=Tg8IQ6ZhPb7eT_sdrLJBgPb2t0cNQ12Hb70yNjUnXIc,12106 +transformers/models/bit/__init__.py,sha256=I9z2RYsPRokD1ycMBRLaesbyMKK4MwLPM5oTles2KmQ,1072 +transformers/models/bit/__pycache__/__init__.cpython-310.pyc,, +transformers/models/bit/__pycache__/configuration_bit.cpython-310.pyc,, +transformers/models/bit/__pycache__/image_processing_bit.cpython-310.pyc,, +transformers/models/bit/__pycache__/image_processing_bit_fast.cpython-310.pyc,, +transformers/models/bit/__pycache__/modeling_bit.cpython-310.pyc,, +transformers/models/bit/configuration_bit.py,sha256=yMlWggmw_iyHiluWsk8SKKlS3kFP-NY8bkyVfKitEJY,6135 +transformers/models/bit/image_processing_bit.py,sha256=QLuBmOegutiWk5nw-gL8XcpBMdwxSHhWz8jR8YtA8aU,15514 +transformers/models/bit/image_processing_bit_fast.py,sha256=3x8ALWaCWTzU2lWyWY6wZHrB5PsbUADef4jj86RXYWg,1312 +transformers/models/bit/modeling_bit.py,sha256=DhkM2rv5De1e2I-dw478m3t8YbHSdfsAD0WBS7Oevm0,28311 +transformers/models/bitnet/__init__.py,sha256=0u3B40Xd6dJ7J7TBxJzSQWcyUe2ZWJTbT6iaWVod_-A,1018 +transformers/models/bitnet/__pycache__/__init__.cpython-310.pyc,, +transformers/models/bitnet/__pycache__/configuration_bitnet.cpython-310.pyc,, +transformers/models/bitnet/__pycache__/modeling_bitnet.cpython-310.pyc,, +transformers/models/bitnet/__pycache__/modular_bitnet.cpython-310.pyc,, +transformers/models/bitnet/configuration_bitnet.py,sha256=aomquZ_YEd01JMTSYhWysjOZRAKxZNlHCaaObCVNxhA,7226 +transformers/models/bitnet/modeling_bitnet.py,sha256=MivRw5d3NMYkixwHuEt6uPKgBj08jo-madsJE9-Wxf4,22532 +transformers/models/bitnet/modular_bitnet.py,sha256=EeBTeac0b1_FCqyY7FCxWS-uE7z0Uetg6kX5EUm8DFc,5672 +transformers/models/blenderbot/__init__.py,sha256=jU3e_DqjuRka882xLbvHUibBwY6ODhrBxmwP08UiLFg,1044 +transformers/models/blenderbot/__pycache__/__init__.cpython-310.pyc,, +transformers/models/blenderbot/__pycache__/configuration_blenderbot.cpython-310.pyc,, +transformers/models/blenderbot/__pycache__/modeling_blenderbot.cpython-310.pyc,, +transformers/models/blenderbot/__pycache__/tokenization_blenderbot.cpython-310.pyc,, +transformers/models/blenderbot/configuration_blenderbot.py,sha256=TF7uKn1n0vzN0Jvp6VNsWkHX154JH0_dVSW04Qh-bZQ,7696 +transformers/models/blenderbot/modeling_blenderbot.py,sha256=J3CGxukzLP184Xb4Z1pQQkrzYdiWsH4A4X8lVl1O6Ng,55518 +transformers/models/blenderbot/tokenization_blenderbot.py,sha256=4BEnkpqvtf6_xwlnfVtHGZPe2fjSfuIyGKjiHBmOZ1w,6884 +transformers/models/blenderbot_small/__init__.py,sha256=d6Zj-S0-76DHKXAjwOdnyU3j2rtUDyktiXP_y0It9l8,1116 +transformers/models/blenderbot_small/__pycache__/__init__.cpython-310.pyc,, +transformers/models/blenderbot_small/__pycache__/configuration_blenderbot_small.cpython-310.pyc,, +transformers/models/blenderbot_small/__pycache__/modeling_blenderbot_small.cpython-310.pyc,, +transformers/models/blenderbot_small/__pycache__/tokenization_blenderbot_small.cpython-310.pyc,, +transformers/models/blenderbot_small/configuration_blenderbot_small.py,sha256=FwHUPU5X8Aiv4uhYqHKb-kRPh-FJXQxVKWrM2ajAocc,7678 +transformers/models/blenderbot_small/modeling_blenderbot_small.py,sha256=msxSRSZO3v0sB77bG27uvtvNRFWxRvIJXGrCy1fip08,55395 +transformers/models/blenderbot_small/tokenization_blenderbot_small.py,sha256=R7MeZBgkSaOAXd7_TDdk4sOBIibYrzN4xElF8y4GS-Q,7944 +transformers/models/blip/__init__.py,sha256=iYvgOjk8ISposmsmPNG-IGUNrR7sZqTT4vCfHUnCLSU,1149 +transformers/models/blip/__pycache__/__init__.cpython-310.pyc,, +transformers/models/blip/__pycache__/configuration_blip.cpython-310.pyc,, +transformers/models/blip/__pycache__/image_processing_blip.cpython-310.pyc,, +transformers/models/blip/__pycache__/image_processing_blip_fast.cpython-310.pyc,, +transformers/models/blip/__pycache__/modeling_blip.cpython-310.pyc,, +transformers/models/blip/__pycache__/modeling_blip_text.cpython-310.pyc,, +transformers/models/blip/__pycache__/processing_blip.cpython-310.pyc,, +transformers/models/blip/configuration_blip.py,sha256=HAgvNcQFCDnvtfX2QztbayBZygmNoz-ytekdVbhZ2gE,14730 +transformers/models/blip/image_processing_blip.py,sha256=Dd3ztTtUth1VHlYAjNGQNp1nV7j5AFfrK9J7DUv3boE,14916 +transformers/models/blip/image_processing_blip_fast.py,sha256=Cu42tOg3ZoBqdoum_7QMkVWXiMTcmMdDtuhGaIpkmKQ,1297 +transformers/models/blip/modeling_blip.py,sha256=uiz9vcOSUo6wj-BUDC7hg_Rfp7RFNeuknB-vBY6cTpc,51460 +transformers/models/blip/modeling_blip_text.py,sha256=W5IDX8dKK0Va7bgUK1ichF8IuZYt5dLXcirYCzBLkBk,39467 +transformers/models/blip/processing_blip.py,sha256=iCW3H4cK8hcVldAymMFxx-chGII87LEngs95uNEuHHw,3061 +transformers/models/blip_2/__init__.py,sha256=kj_6H0rQ7dLoQk-COIb06LlDRnbORu3GLU3m4EdMkAM,1030 +transformers/models/blip_2/__pycache__/__init__.cpython-310.pyc,, +transformers/models/blip_2/__pycache__/configuration_blip_2.cpython-310.pyc,, +transformers/models/blip_2/__pycache__/modeling_blip_2.cpython-310.pyc,, +transformers/models/blip_2/__pycache__/processing_blip_2.cpython-310.pyc,, +transformers/models/blip_2/configuration_blip_2.py,sha256=iSKUbMgRX8j_Gx4EZOBSnNS3-j12HWlfGJzQCfdnXr4,14650 +transformers/models/blip_2/modeling_blip_2.py,sha256=PiO0Ovg-ryxf94StqYAjLgjMhD54waPQ3CGNfRYf188,87838 +transformers/models/blip_2/processing_blip_2.py,sha256=5VOE__t-z0fuNCxpKcDJXOH8bqpKACIsCMwvADd856Q,4813 +transformers/models/bloom/__init__.py,sha256=hVsmMQEVK2LVTQd_zlExF9SJjdMLX7pjgFVP6lKg2IY,1029 +transformers/models/bloom/__pycache__/__init__.cpython-310.pyc,, +transformers/models/bloom/__pycache__/configuration_bloom.cpython-310.pyc,, +transformers/models/bloom/__pycache__/modeling_bloom.cpython-310.pyc,, +transformers/models/bloom/configuration_bloom.py,sha256=CiD2g-DUaCY0lSbJijDPBe5XDVxBn5x9r_BaFdz-q-s,6436 +transformers/models/bloom/modeling_bloom.py,sha256=LJqXF-MDphHB47dBzCqB_IFb7rRHTb_zzB1uiW0hBCU,42217 +transformers/models/blt/__init__.py,sha256=Eg5lWtgdEQ8Yld6WH0R7-x3R6hnVQJFqUMEuAooZOyo,1023 +transformers/models/blt/__pycache__/__init__.cpython-310.pyc,, +transformers/models/blt/__pycache__/configuration_blt.cpython-310.pyc,, +transformers/models/blt/__pycache__/modeling_blt.cpython-310.pyc,, +transformers/models/blt/__pycache__/modular_blt.cpython-310.pyc,, +transformers/models/blt/configuration_blt.py,sha256=vkIQI0QAqf6ap8u-F6SImACH-EL_g0rCor36OTpyFEc,19735 +transformers/models/blt/modeling_blt.py,sha256=3sRuBuZ1j9jG1gGAHvAxORw-JzCFw4dJJZ7WHEGsY18,64769 +transformers/models/blt/modular_blt.py,sha256=IabL5bPUTta9RTtbYqcIQMJxNPqTaMdczaMcaYlYt-M,51161 +transformers/models/bridgetower/__init__.py,sha256=S9u22GAHi1LVcS3OYGBzfBVTjDvk_WU9JZGPTEo6zxw,1146 +transformers/models/bridgetower/__pycache__/__init__.cpython-310.pyc,, +transformers/models/bridgetower/__pycache__/configuration_bridgetower.cpython-310.pyc,, +transformers/models/bridgetower/__pycache__/image_processing_bridgetower.cpython-310.pyc,, +transformers/models/bridgetower/__pycache__/image_processing_bridgetower_fast.cpython-310.pyc,, +transformers/models/bridgetower/__pycache__/modeling_bridgetower.cpython-310.pyc,, +transformers/models/bridgetower/__pycache__/processing_bridgetower.cpython-310.pyc,, +transformers/models/bridgetower/configuration_bridgetower.py,sha256=H0eyJOMhM-ES-Kr7zi8iUUtuVc7_wckk7somKfpmYFU,14058 +transformers/models/bridgetower/image_processing_bridgetower.py,sha256=q8BAajTkrcg06znbJdpZqplTNfYNVplunx61ddXxYDw,25812 +transformers/models/bridgetower/image_processing_bridgetower_fast.py,sha256=fMj7j_APJxVQn9i94WDNdXjmIupl8THc5YNzRPByCwM,9583 +transformers/models/bridgetower/modeling_bridgetower.py,sha256=f7fK6P_eqINeBxjzrr-O_Fi5pbF-49KvgriXBcJWd8w,81821 +transformers/models/bridgetower/processing_bridgetower.py,sha256=pPLA_1cSpsz5S6BfddtG4JSdJdN4pWlP89mksXfGRsQ,1617 +transformers/models/bros/__init__.py,sha256=wT0avJ_J50-WK6jOB-6UbgN5kjHiBwG-NNT_iefMXr8,1024 +transformers/models/bros/__pycache__/__init__.cpython-310.pyc,, +transformers/models/bros/__pycache__/configuration_bros.cpython-310.pyc,, +transformers/models/bros/__pycache__/modeling_bros.cpython-310.pyc,, +transformers/models/bros/__pycache__/processing_bros.cpython-310.pyc,, +transformers/models/bros/configuration_bros.py,sha256=5h7Oj__BF7DKA4acy3drVutbpV-uYoIpkb6rpMyePT0,6872 +transformers/models/bros/modeling_bros.py,sha256=Tdqk_alf8Slkws7GJXRF_U6phfs630NQJ1pgH8rc0yQ,44196 +transformers/models/bros/processing_bros.py,sha256=dUxWojDc6X766HgXqRFZxb7PeJ8q_sKs1krsZSPhyWw,1467 +transformers/models/byt5/__init__.py,sha256=O7yXvHyqMZ7stkKX67knnddmJ81pPHoKrY_7NCAauU4,955 +transformers/models/byt5/__pycache__/__init__.cpython-310.pyc,, +transformers/models/byt5/__pycache__/tokenization_byt5.cpython-310.pyc,, +transformers/models/byt5/tokenization_byt5.py,sha256=hAt4Eic6Hgb8HBKwDq_Tg1MZmWhRtgYXaNRUFFGz6kw,9992 +transformers/models/camembert/__init__.py,sha256=-akJBxnuua6C8t5logymVZJ5dvX9-5ADk93h0cU3d64,1041 +transformers/models/camembert/__pycache__/__init__.cpython-310.pyc,, +transformers/models/camembert/__pycache__/configuration_camembert.cpython-310.pyc,, +transformers/models/camembert/__pycache__/modeling_camembert.cpython-310.pyc,, +transformers/models/camembert/__pycache__/modular_camembert.cpython-310.pyc,, +transformers/models/camembert/__pycache__/tokenization_camembert.cpython-310.pyc,, +transformers/models/camembert/configuration_camembert.py,sha256=QdkH5vQ0jHwmyZHgEhYWjFIDfUBQ_gTRmGE4VDZCfko,6190 +transformers/models/camembert/modeling_camembert.py,sha256=ehkj8weFLvAwnzoLZSoBgTpKKNN3aXTviUb0DJqpgvA,54856 +transformers/models/camembert/modular_camembert.py,sha256=AJw1GzwklD9n_TkNFXLAtIUOH00U6s3X_WegZ7iqVgg,22686 +transformers/models/camembert/tokenization_camembert.py,sha256=pnUHPAJBqhagZFHuUu8lEt_7HlWmnIwTaTQHRViJ59U,7321 +transformers/models/canine/__init__.py,sha256=ThkEqO6wPzWCnAplx0EWCUqVaKKsNYQKXQhWfTblEBU,1032 +transformers/models/canine/__pycache__/__init__.cpython-310.pyc,, +transformers/models/canine/__pycache__/configuration_canine.cpython-310.pyc,, +transformers/models/canine/__pycache__/modeling_canine.cpython-310.pyc,, +transformers/models/canine/__pycache__/tokenization_canine.cpython-310.pyc,, +transformers/models/canine/configuration_canine.py,sha256=GeD99sGEi2LnW012m3ur7ehMpbKcFmLTOmaPRE1kx_Q,6611 +transformers/models/canine/modeling_canine.py,sha256=tx7apZszRqSAXsg0lkbw_8tmxcrjHgWzMztEwg1rOcA,58720 +transformers/models/canine/tokenization_canine.py,sha256=hoJ8hVXuy7aibySanfuOdbOV6aOt43myk_jounws-OY,5932 +transformers/models/chameleon/__init__.py,sha256=EJ5kOvTyCFQjjWv9h4CMGHDRjQZ3CJ6j9Ygk2bEylA0,1136 +transformers/models/chameleon/__pycache__/__init__.cpython-310.pyc,, +transformers/models/chameleon/__pycache__/configuration_chameleon.cpython-310.pyc,, +transformers/models/chameleon/__pycache__/image_processing_chameleon.cpython-310.pyc,, +transformers/models/chameleon/__pycache__/image_processing_chameleon_fast.cpython-310.pyc,, +transformers/models/chameleon/__pycache__/modeling_chameleon.cpython-310.pyc,, +transformers/models/chameleon/__pycache__/processing_chameleon.cpython-310.pyc,, +transformers/models/chameleon/configuration_chameleon.py,sha256=ORLLKiBFeKyrBgSLCRQkF0iPq1v2_qYeKwI7iAGdFNU,12100 +transformers/models/chameleon/image_processing_chameleon.py,sha256=GphMeboa0KytveIag4y2AQ2UoZ2NjRU4Ix5YBrnE-wY,16519 +transformers/models/chameleon/image_processing_chameleon_fast.py,sha256=E0SOez2vLJUWeIWUi8ks3ULUDF5ejcOTLuIwaPPSzxo,4032 +transformers/models/chameleon/modeling_chameleon.py,sha256=d4BZBYcyyfmweIVwK24CLJjI3YfQGQikwVaDcVgjnbM,52333 +transformers/models/chameleon/processing_chameleon.py,sha256=Z8qzTqlRKo86Y9VVqXT5Fdcy4Dcgm7-GhYPD2keDU24,7136 +transformers/models/chinese_clip/__init__.py,sha256=-koN80ZGdGEDnTkLDGSDlzQ3fZcahTtaOgjtl3sddSE,1202 +transformers/models/chinese_clip/__pycache__/__init__.cpython-310.pyc,, +transformers/models/chinese_clip/__pycache__/configuration_chinese_clip.cpython-310.pyc,, +transformers/models/chinese_clip/__pycache__/image_processing_chinese_clip.cpython-310.pyc,, +transformers/models/chinese_clip/__pycache__/image_processing_chinese_clip_fast.cpython-310.pyc,, +transformers/models/chinese_clip/__pycache__/modeling_chinese_clip.cpython-310.pyc,, +transformers/models/chinese_clip/__pycache__/processing_chinese_clip.cpython-310.pyc,, +transformers/models/chinese_clip/configuration_chinese_clip.py,sha256=IAveqbQwwunXzO0qm1pRhOxWJkeLfgZ8rvOh6W5H8po,18012 +transformers/models/chinese_clip/image_processing_chinese_clip.py,sha256=blnbqNK1DjZnokbnace6XFyZZDDI8TAIeswnrTmRha8,15150 +transformers/models/chinese_clip/image_processing_chinese_clip_fast.py,sha256=TE5c6k3nSWlLODKO86ANI1PFiIqvzAAKVPJFv4x-Y4U,1332 +transformers/models/chinese_clip/modeling_chinese_clip.py,sha256=jT7cE1mOyG9ryvJQJfQVpGhCait4nKK6tXP-MSuCWf8,49976 +transformers/models/chinese_clip/processing_chinese_clip.py,sha256=JAPbqZs4NVJCTDXTRh8kZvKh0IPxNG5CU_nKKQRgrp0,995 +transformers/models/clap/__init__.py,sha256=751udHbsD7FBLGAByjx_8Z4XPLly1MaQQ4wKN_9vbOY,1067 +transformers/models/clap/__pycache__/__init__.cpython-310.pyc,, +transformers/models/clap/__pycache__/configuration_clap.cpython-310.pyc,, +transformers/models/clap/__pycache__/feature_extraction_clap.cpython-310.pyc,, +transformers/models/clap/__pycache__/modeling_clap.cpython-310.pyc,, +transformers/models/clap/__pycache__/processing_clap.cpython-310.pyc,, +transformers/models/clap/configuration_clap.py,sha256=_nxTAMxdrLj5pVfHmxK-CnsBI7HJm5WQBPHREQ5r4zM,17366 +transformers/models/clap/feature_extraction_clap.py,sha256=orx0svfj0Ru3BLnnaZcF4tW_5iQAN18YAg3ab3OC20U,18699 +transformers/models/clap/modeling_clap.py,sha256=fWsDlaw43VvcoyKRoG2bGtF7XG6nuDLikZp5QBLixvk,79439 +transformers/models/clap/processing_clap.py,sha256=f85IpsPResgKvu7LTfKRuVG3ny-J57bRzpDlfN6Y_aE,961 +transformers/models/clip/__init__.py,sha256=aW_KGBn-oJBYJVdBCey5mj8f8u00nBiEzigid2aLY7o,1191 +transformers/models/clip/__pycache__/__init__.cpython-310.pyc,, +transformers/models/clip/__pycache__/configuration_clip.cpython-310.pyc,, +transformers/models/clip/__pycache__/image_processing_clip.cpython-310.pyc,, +transformers/models/clip/__pycache__/image_processing_clip_fast.cpython-310.pyc,, +transformers/models/clip/__pycache__/modeling_clip.cpython-310.pyc,, +transformers/models/clip/__pycache__/processing_clip.cpython-310.pyc,, +transformers/models/clip/__pycache__/tokenization_clip.cpython-310.pyc,, +transformers/models/clip/configuration_clip.py,sha256=IKB-7RFYGoCnVUOcNdg7sAMZkago4AmRyBAB-79Fjw0,17366 +transformers/models/clip/image_processing_clip.py,sha256=Tpa-HLujorLV7_6aLRTVJ1hB7wKaunxDMcsaaaGYcC4,16611 +transformers/models/clip/image_processing_clip_fast.py,sha256=Ch5n7XYOFW6UOZv9-2CZBbSX0Iy0XydXh-VlD3lEggs,1805 +transformers/models/clip/modeling_clip.py,sha256=p1EScYnfgqCfC9BybkqZcZAromRQ4YHrzenVLJVZZGw,44295 +transformers/models/clip/processing_clip.py,sha256=Um6KNOUZ3pksQqCKrMbAXqaJewINGkmH2E5qkY78czI,928 +transformers/models/clip/tokenization_clip.py,sha256=-1M4oNko3rlHC8hNSTL7LWRWYR8c4U_xFAjMPsbwHvc,5202 +transformers/models/clipseg/__init__.py,sha256=12Y-b3sRDKM3Hy8-6rK4GUF2a91V1S3nLUF7559AALw,1033 +transformers/models/clipseg/__pycache__/__init__.cpython-310.pyc,, +transformers/models/clipseg/__pycache__/configuration_clipseg.cpython-310.pyc,, +transformers/models/clipseg/__pycache__/modeling_clipseg.cpython-310.pyc,, +transformers/models/clipseg/__pycache__/processing_clipseg.cpython-310.pyc,, +transformers/models/clipseg/configuration_clipseg.py,sha256=uQAdtGjC9qknR-MNjuJ-aHmJ6ifUOoSljXZOjVuW4pA,19076 +transformers/models/clipseg/modeling_clipseg.py,sha256=dE9l2uYNbdQXwEQOX8F8BXLKnhm2sLY7IFE0xpai6aY,56457 +transformers/models/clipseg/processing_clipseg.py,sha256=LwTtI7ddVol3tUk8IhkSwCheSSmRBD5OFqW7ssGzpaQ,3932 +transformers/models/clvp/__init__.py,sha256=RRnPofxkr_llgSxCP9tcAhu3xCR7E_m1PkrHv7KLMzo,1104 +transformers/models/clvp/__pycache__/__init__.cpython-310.pyc,, +transformers/models/clvp/__pycache__/configuration_clvp.cpython-310.pyc,, +transformers/models/clvp/__pycache__/feature_extraction_clvp.cpython-310.pyc,, +transformers/models/clvp/__pycache__/modeling_clvp.cpython-310.pyc,, +transformers/models/clvp/__pycache__/number_normalizer.cpython-310.pyc,, +transformers/models/clvp/__pycache__/processing_clvp.cpython-310.pyc,, +transformers/models/clvp/__pycache__/tokenization_clvp.cpython-310.pyc,, +transformers/models/clvp/configuration_clvp.py,sha256=JWhcgqjViVdqu0Rfgi24RQp9M7_dk8BD0F0UEj6r-8c,19781 +transformers/models/clvp/feature_extraction_clvp.py,sha256=5v9w0dCsEF9UVvpMvt98OkBbdRBbAZbuh28DiJmdgxE,10851 +transformers/models/clvp/modeling_clvp.py,sha256=PJXVwkH7nYjQJoKe1MJnHRC_dULCytfJbO2wsVZukFw,85088 +transformers/models/clvp/number_normalizer.py,sha256=KLJC2bIft4UKZrQVM8zisA70vOeJlHI1jtbV1xVIjd8,8918 +transformers/models/clvp/processing_clvp.py,sha256=1u5mgmf1tmUdDwITZUG_GTbon6TTOcZNCa7Ek5Cr2EY,1345 +transformers/models/clvp/tokenization_clvp.py,sha256=om3tlQSKLb-fasG20VMamRMrxTAszRcxJ2PtMYA6Vfo,10181 +transformers/models/code_llama/__init__.py,sha256=vitmyj4qzyn4U2NOEZcp0LhLYGSN4PWHXm8L_UCbvsU,961 +transformers/models/code_llama/__pycache__/__init__.cpython-310.pyc,, +transformers/models/code_llama/__pycache__/tokenization_code_llama.cpython-310.pyc,, +transformers/models/code_llama/tokenization_code_llama.py,sha256=Dc-FsYs5EItOG3d1B3VCTDjFzA82xYHYh-uAm37nEFQ,15116 +transformers/models/codegen/__init__.py,sha256=KofDAB0YGRrmc5s6s8TS9ColIyx-a6_AUeBzZbTQqrY,1114 +transformers/models/codegen/__pycache__/__init__.cpython-310.pyc,, +transformers/models/codegen/__pycache__/configuration_codegen.cpython-310.pyc,, +transformers/models/codegen/__pycache__/modeling_codegen.cpython-310.pyc,, +transformers/models/codegen/__pycache__/tokenization_codegen.cpython-310.pyc,, +transformers/models/codegen/configuration_codegen.py,sha256=ne9QBpA-sx-cn1wZPUaIsrElsTcUOTHCECYJL5Z52Ko,6215 +transformers/models/codegen/modeling_codegen.py,sha256=BliW4UCXOq585zlzpdEEjoPdUkVkI-C39fHgQmYQnco,21097 +transformers/models/codegen/tokenization_codegen.py,sha256=uO-6sBK0bcRJ-p74gvNHP30SJSc-NaINzJWlvIlSgvw,8512 +transformers/models/cohere/__init__.py,sha256=ODwuQ7yp4l1fhMjzk_yO5EAmCzXh1cNOmf10iBD3H9A,1032 +transformers/models/cohere/__pycache__/__init__.cpython-310.pyc,, +transformers/models/cohere/__pycache__/configuration_cohere.cpython-310.pyc,, +transformers/models/cohere/__pycache__/modeling_cohere.cpython-310.pyc,, +transformers/models/cohere/__pycache__/modular_cohere.cpython-310.pyc,, +transformers/models/cohere/__pycache__/tokenization_cohere.cpython-310.pyc,, +transformers/models/cohere/configuration_cohere.py,sha256=wgSkhIO1RY3ulb-natgHygEEppA6XIh7FLQu9NXP168,8545 +transformers/models/cohere/modeling_cohere.py,sha256=KDRamyJqMAgcq0z9yDh7ZDjaACTC7K_PoCGY1bT8fOE,25317 +transformers/models/cohere/modular_cohere.py,sha256=zCqPlaHLHSnoq7a2gp_OFhTMqHzFnQW_8ySylLI3XW4,15635 +transformers/models/cohere/tokenization_cohere.py,sha256=Cqhqs5wcCt9bennRPaaNTMC0cw3F6BalIWjXna72O4E,19625 +transformers/models/cohere2/__init__.py,sha256=6Cx_c-uTSNopbO3NLWCgMmEB2-5hzkrunUWmMrb8YSU,1011 +transformers/models/cohere2/__pycache__/__init__.cpython-310.pyc,, +transformers/models/cohere2/__pycache__/configuration_cohere2.cpython-310.pyc,, +transformers/models/cohere2/__pycache__/modeling_cohere2.cpython-310.pyc,, +transformers/models/cohere2/__pycache__/modular_cohere2.cpython-310.pyc,, +transformers/models/cohere2/configuration_cohere2.py,sha256=QYW0vf6CpnSA7voHRHyhzBexWEej8wy1vFAxKAvvKyQ,10022 +transformers/models/cohere2/modeling_cohere2.py,sha256=BJNR5EMvU_RedVddshQj3gzIE76P2OC68GMYaTafdGw,24697 +transformers/models/cohere2/modular_cohere2.py,sha256=vW1ckpLayy_yiBOKNcBMHWAphxLtnksZro-NQ3NVTP0,18575 +transformers/models/cohere2_vision/__init__.py,sha256=VZPnI0ugmeUt8tHNLXhSF1X4maFa0T4pqnm3VAPEyo0,1110 +transformers/models/cohere2_vision/__pycache__/__init__.cpython-310.pyc,, +transformers/models/cohere2_vision/__pycache__/configuration_cohere2_vision.cpython-310.pyc,, +transformers/models/cohere2_vision/__pycache__/image_processing_cohere2_vision_fast.cpython-310.pyc,, +transformers/models/cohere2_vision/__pycache__/modeling_cohere2_vision.cpython-310.pyc,, +transformers/models/cohere2_vision/__pycache__/modular_cohere2_vision.cpython-310.pyc,, +transformers/models/cohere2_vision/__pycache__/processing_cohere2_vision.cpython-310.pyc,, +transformers/models/cohere2_vision/configuration_cohere2_vision.py,sha256=hHHHIM9CeQntpqtPUiy6lGYx-N-_Id0_1oi45HQV2HA,3735 +transformers/models/cohere2_vision/image_processing_cohere2_vision_fast.py,sha256=vSnNNijQ-wpdjEzY2eymG3CugWBAoN6lTUJvt9X3fr4,13569 +transformers/models/cohere2_vision/modeling_cohere2_vision.py,sha256=V6IvHPmN17ojJ-3Bs9M8dBRbStPpb-vsj--TX6nW4nM,17783 +transformers/models/cohere2_vision/modular_cohere2_vision.py,sha256=mCi6SXlt2ZdzEisGgaXfgSSiXlFAJyrMcUV5d7LsOUc,14252 +transformers/models/cohere2_vision/processing_cohere2_vision.py,sha256=3ZMWbNSBcZ8HOFDh7AQc6w36MJo15wrFbY-0tW7x73M,7239 +transformers/models/colmodernvbert/__init__.py,sha256=ZFaJLo1i7A4zZ-Sf7BxZZGcoKMjFXCgQUetP4TXs2Ig,1099 +transformers/models/colmodernvbert/__pycache__/__init__.cpython-310.pyc,, +transformers/models/colmodernvbert/__pycache__/configuration_colmodernvbert.cpython-310.pyc,, +transformers/models/colmodernvbert/__pycache__/modeling_colmodernvbert.cpython-310.pyc,, +transformers/models/colmodernvbert/__pycache__/modular_colmodernvbert.cpython-310.pyc,, +transformers/models/colmodernvbert/__pycache__/processing_colmodernvbert.cpython-310.pyc,, +transformers/models/colmodernvbert/configuration_colmodernvbert.py,sha256=MXEc3gA_C7UajjYK6_ECFq5V4dYRhgz67d533BZd0mU,4758 +transformers/models/colmodernvbert/modeling_colmodernvbert.py,sha256=mWV0sdfKvXpD7YOavJO9CkJVTJU25ph2EbYtZotDLbk,8509 +transformers/models/colmodernvbert/modular_colmodernvbert.py,sha256=lrHI71KBFJp5e0_13dP53HYciK2qEzbcLrvsokF9Kqo,20340 +transformers/models/colmodernvbert/processing_colmodernvbert.py,sha256=uwLWB56uZSiLk2v6KfprFbnXlrKMt_YVqFO9jhC3IDI,26230 +transformers/models/colpali/__init__.py,sha256=eG-nOojo-DPkgZJACn6hbJqqfnGE97uKmLkpWVin66A,1033 +transformers/models/colpali/__pycache__/__init__.cpython-310.pyc,, +transformers/models/colpali/__pycache__/configuration_colpali.cpython-310.pyc,, +transformers/models/colpali/__pycache__/modeling_colpali.cpython-310.pyc,, +transformers/models/colpali/__pycache__/modular_colpali.cpython-310.pyc,, +transformers/models/colpali/__pycache__/processing_colpali.cpython-310.pyc,, +transformers/models/colpali/configuration_colpali.py,sha256=hKl3OOp_w3tSZzOWKYBqJwZ02O_wO_6pssrNO5vq00g,4285 +transformers/models/colpali/modeling_colpali.py,sha256=pb31s9WIOIzU1XsZ8nGBLvaJOa7UBZO1OmzQD4wmVaM,8600 +transformers/models/colpali/modular_colpali.py,sha256=V_a8F8rJLrPZKi4T7_C1HCKDfStL-66eiQk9apmWE8E,12861 +transformers/models/colpali/processing_colpali.py,sha256=ar5_XMFiEkU9rVroi-89Lvf4EqCmbLqq322-1_qIJcU,16492 +transformers/models/colqwen2/__init__.py,sha256=GBrOYGkXcXTOuCd6AhVMss6TVb2igEKFcrAkgJbbg-Q,1036 +transformers/models/colqwen2/__pycache__/__init__.cpython-310.pyc,, +transformers/models/colqwen2/__pycache__/configuration_colqwen2.cpython-310.pyc,, +transformers/models/colqwen2/__pycache__/modeling_colqwen2.cpython-310.pyc,, +transformers/models/colqwen2/__pycache__/modular_colqwen2.cpython-310.pyc,, +transformers/models/colqwen2/__pycache__/processing_colqwen2.cpython-310.pyc,, +transformers/models/colqwen2/configuration_colqwen2.py,sha256=uStnTnom3s4wvmHKTX6P_57HSiM6KhdV163G0MCuQmc,3791 +transformers/models/colqwen2/modeling_colqwen2.py,sha256=dn1XQW7fR96lEAMRVEvxUfxU9PCNnuMmvlowSxs3FYs,10760 +transformers/models/colqwen2/modular_colqwen2.py,sha256=5J2RWyBpG9_8pPk2c89ZcyJMtzygIGR_EVUpTOn4z6I,15739 +transformers/models/colqwen2/processing_colqwen2.py,sha256=xXZNbruZo1MTE2qSJ6dIwPZR6O5zOeRMzGRI4A0OJTg,16656 +transformers/models/conditional_detr/__init__.py,sha256=p8luCb38qMZvKdI7GLvBTx1eiKGFMv8Obd5iKaqoVe8,1179 +transformers/models/conditional_detr/__pycache__/__init__.cpython-310.pyc,, +transformers/models/conditional_detr/__pycache__/configuration_conditional_detr.cpython-310.pyc,, +transformers/models/conditional_detr/__pycache__/image_processing_conditional_detr.cpython-310.pyc,, +transformers/models/conditional_detr/__pycache__/image_processing_conditional_detr_fast.cpython-310.pyc,, +transformers/models/conditional_detr/__pycache__/modeling_conditional_detr.cpython-310.pyc,, +transformers/models/conditional_detr/__pycache__/modular_conditional_detr.cpython-310.pyc,, +transformers/models/conditional_detr/configuration_conditional_detr.py,sha256=Hz4hdVVynOroMhQmxqYHVgJUvm6uXcYXLQStozXJLkU,10861 +transformers/models/conditional_detr/image_processing_conditional_detr.py,sha256=ZRmciRWzZ94-hLqwSDchDLtpo95yQqR4mq_9gIvqRj4,79605 +transformers/models/conditional_detr/image_processing_conditional_detr_fast.py,sha256=Isoq18RKyl4-jHyVEPJ_ejuUQ4OpjKm02j9wtPQ1rtE,41240 +transformers/models/conditional_detr/modeling_conditional_detr.py,sha256=R2qioFVxgIJgNV4xB78tdxTBvhV8PitA0k_avTPmAgI,85469 +transformers/models/conditional_detr/modular_conditional_detr.py,sha256=dYcqgQnAqiDRmk1gqRdKaY1ogskUe1JvNhkaIp1hNIU,44737 +transformers/models/convbert/__init__.py,sha256=Y0-hcRZvFjmIVqDFCtOKhQDRqp0d7wKCZc10seKejqI,1118 +transformers/models/convbert/__pycache__/__init__.cpython-310.pyc,, +transformers/models/convbert/__pycache__/configuration_convbert.cpython-310.pyc,, +transformers/models/convbert/__pycache__/modeling_convbert.cpython-310.pyc,, +transformers/models/convbert/__pycache__/tokenization_convbert.cpython-310.pyc,, +transformers/models/convbert/configuration_convbert.py,sha256=fOCTwKxRIgodaKtPCgTXrB6kvVVk66n_ol2ELely18I,6358 +transformers/models/convbert/modeling_convbert.py,sha256=Ysht8PJQtWnQugEUbYRNak4YCzMoJhcjtA74gl5NNUE,48940 +transformers/models/convbert/tokenization_convbert.py,sha256=x-ytkim2fLoFmpF9-VgIEuigm6tggJLwkaSsC1_radg,1092 +transformers/models/convnext/__init__.py,sha256=VPV1GFqj2NaPR0h-sDQL_tafoXLmUbgb6LcKN1oViVY,1139 +transformers/models/convnext/__pycache__/__init__.cpython-310.pyc,, +transformers/models/convnext/__pycache__/configuration_convnext.cpython-310.pyc,, +transformers/models/convnext/__pycache__/image_processing_convnext.cpython-310.pyc,, +transformers/models/convnext/__pycache__/image_processing_convnext_fast.cpython-310.pyc,, +transformers/models/convnext/__pycache__/modeling_convnext.cpython-310.pyc,, +transformers/models/convnext/configuration_convnext.py,sha256=PnESDYeCBz40WJqcWNDdKWMDSSAZ2cb_Ngxoxg54ZRk,5471 +transformers/models/convnext/image_processing_convnext.py,sha256=M-_VmG0-qHcLtgF6qT4ge70w3L59KfZxj38qCudYmas,15989 +transformers/models/convnext/image_processing_convnext_fast.py,sha256=IGmuh0P_nj7mbxOISBjbRTJw6yH87PJBCRwELsJZ0rU,6611 +transformers/models/convnext/modeling_convnext.py,sha256=m91JjPIO_Igj5SdG3h981vfEi4Qft5d_7JQBjpmHGhU,16155 +transformers/models/convnextv2/__init__.py,sha256=WcvDfW6VT_st_i235oLAM_okTePdPNtxNVHsOZ4_Bi4,1001 +transformers/models/convnextv2/__pycache__/__init__.cpython-310.pyc,, +transformers/models/convnextv2/__pycache__/configuration_convnextv2.cpython-310.pyc,, +transformers/models/convnextv2/__pycache__/modeling_convnextv2.cpython-310.pyc,, +transformers/models/convnextv2/configuration_convnextv2.py,sha256=1vA89oXl-O746q-L4_pHtsMWkBVZpDoNFLBa4AYB24o,5404 +transformers/models/convnextv2/modeling_convnextv2.py,sha256=EWrWKPai-Jb36CeQiJNOETydkvYwnxjKLnPgEH6oe7s,17637 +transformers/models/cpm/__init__.py,sha256=psXgdNRVfFj8JbyWxWhM84oflsqVA5_ODqYatXvkpzU,954 +transformers/models/cpm/__pycache__/__init__.cpython-310.pyc,, +transformers/models/cpm/__pycache__/tokenization_cpm.cpython-310.pyc,, +transformers/models/cpm/__pycache__/tokenization_cpm_fast.cpython-310.pyc,, +transformers/models/cpm/tokenization_cpm.py,sha256=XCOcTehy4nF7oE1K5m_b2oXGYoz6i8D0Mf8T-KEa06Y,13822 +transformers/models/cpm/tokenization_cpm_fast.py,sha256=kO2p2Z3rthXylnGlz0QKFhBe2vjGRSnsdVxP69qKVBU,9917 +transformers/models/cpmant/__init__.py,sha256=RfkbbhNqdbioJ5XVaTtxBLnZRt1GFnXugS3UFXHYV0c,1032 +transformers/models/cpmant/__pycache__/__init__.cpython-310.pyc,, +transformers/models/cpmant/__pycache__/configuration_cpmant.cpython-310.pyc,, +transformers/models/cpmant/__pycache__/modeling_cpmant.cpython-310.pyc,, +transformers/models/cpmant/__pycache__/tokenization_cpmant.cpython-310.pyc,, +transformers/models/cpmant/configuration_cpmant.py,sha256=pKqNPHTW5U0Tmct9utAeWq6MZ0NUr0ilaMPd9U29Sxw,5334 +transformers/models/cpmant/modeling_cpmant.py,sha256=HvZgKpC1DZ3EE2zpLhDxFxzkQUi0d8-E72KKvCiMg4Y,32343 +transformers/models/cpmant/tokenization_cpmant.py,sha256=7y32Z-rvAP2lv8eoz6qyU6cht69VgtytfN-VMfL5b6A,7993 +transformers/models/csm/__init__.py,sha256=n-AQHwxZwD8imEHipiQoTDRf_OMo5zJhQ0tKKWMCPYs,1021 +transformers/models/csm/__pycache__/__init__.cpython-310.pyc,, +transformers/models/csm/__pycache__/configuration_csm.cpython-310.pyc,, +transformers/models/csm/__pycache__/generation_csm.cpython-310.pyc,, +transformers/models/csm/__pycache__/modeling_csm.cpython-310.pyc,, +transformers/models/csm/__pycache__/modular_csm.cpython-310.pyc,, +transformers/models/csm/__pycache__/processing_csm.cpython-310.pyc,, +transformers/models/csm/configuration_csm.py,sha256=ZHxbFuFfm_0M4KP2H-FAyH7_zPc55WderUamiuRomF4,18227 +transformers/models/csm/generation_csm.py,sha256=Ozs3uBL8a8YlW_LeSpgH8FFThqj5rdVVqtzQIRtZ9xw,25588 +transformers/models/csm/modeling_csm.py,sha256=e6xGf9zakQuKUP7lr_6ur1dp31jsBb_PjXHh-cKsE7M,52055 +transformers/models/csm/modular_csm.py,sha256=eOglky9mt4YWqc9aA-19qX2T6r_64OCl3rcY7pzlTrA,35529 +transformers/models/csm/processing_csm.py,sha256=v6WkNkanMqvF3vAZ5KACKpzSmy-x7bbkfMVUN3RIVl0,13710 +transformers/models/ctrl/__init__.py,sha256=Uj8X4puguEkwCqBv_qOznsAW6GPOlieWNi-IGUh6mBQ,1026 +transformers/models/ctrl/__pycache__/__init__.cpython-310.pyc,, +transformers/models/ctrl/__pycache__/configuration_ctrl.cpython-310.pyc,, +transformers/models/ctrl/__pycache__/modeling_ctrl.cpython-310.pyc,, +transformers/models/ctrl/__pycache__/tokenization_ctrl.cpython-310.pyc,, +transformers/models/ctrl/configuration_ctrl.py,sha256=6JzjBOF4O3OZLQIVBfEoWwFx15tWNRo2g35C4eUWsGs,5271 +transformers/models/ctrl/modeling_ctrl.py,sha256=ry71FkxK2aIo9vYHjiC99PioMJS61wtKLKXrpHKI_mo,27314 +transformers/models/ctrl/tokenization_ctrl.py,sha256=BFU4oTzkz9G141xRPHYJRXMMuY1Jv_CsBitg-Jf2VL4,6855 +transformers/models/cvt/__init__.py,sha256=PWfHQ1umBPnzjBcUQnJn2YvYAqxyWu8YrGzqmDsSHJo,987 +transformers/models/cvt/__pycache__/__init__.cpython-310.pyc,, +transformers/models/cvt/__pycache__/configuration_cvt.cpython-310.pyc,, +transformers/models/cvt/__pycache__/modeling_cvt.cpython-310.pyc,, +transformers/models/cvt/configuration_cvt.py,sha256=uotXWRSaU5wDQnBxPxeYHH8wpignkq7o9z3LIOccw8Q,6669 +transformers/models/cvt/modeling_cvt.py,sha256=5Oce_dXnRdPeCYeGIzAJ-xwGBcswsBDx15f-Ciu5vvM,24148 +transformers/models/cwm/__init__.py,sha256=03y-UaFJQwrYUyzQX5j0e7reFrGcd7uD93fnOrUsJSA,988 +transformers/models/cwm/__pycache__/__init__.cpython-310.pyc,, +transformers/models/cwm/__pycache__/configuration_cwm.cpython-310.pyc,, +transformers/models/cwm/__pycache__/modeling_cwm.cpython-310.pyc,, +transformers/models/cwm/__pycache__/modular_cwm.cpython-310.pyc,, +transformers/models/cwm/configuration_cwm.py,sha256=vozL5JNdO7K48UpC1ACMsqhTxYL4RhxvQoD6LvtyR3s,9612 +transformers/models/cwm/modeling_cwm.py,sha256=C28S7oagSSIMNu8U9cA8ZT9OmB_wAq--ErwQrbYn0L0,22291 +transformers/models/cwm/modular_cwm.py,sha256=RNncqPNbcj5l-Z5rz4zabkWv3lEHsfEZQdPEZWkJd2o,12634 +transformers/models/d_fine/__init__.py,sha256=1gNscomeWytwZT7K2GJBwyXxDkfVNLhRjuDwyde2A0s,995 +transformers/models/d_fine/__pycache__/__init__.cpython-310.pyc,, +transformers/models/d_fine/__pycache__/configuration_d_fine.cpython-310.pyc,, +transformers/models/d_fine/__pycache__/modeling_d_fine.cpython-310.pyc,, +transformers/models/d_fine/__pycache__/modular_d_fine.cpython-310.pyc,, +transformers/models/d_fine/configuration_d_fine.py,sha256=alh3H511safWNkWtjE94CRNuXIO8ccj7IOQgpGF_NsM,19358 +transformers/models/d_fine/modeling_d_fine.py,sha256=HLhjPFQVk667cx1IROap5l3-eSVtyty4P9jqNdH1OYU,95218 +transformers/models/d_fine/modular_d_fine.py,sha256=UwT08Dqa4rEagRYtcA727QQ-7Sr7QhrNP4weffhFQ0U,52948 +transformers/models/dab_detr/__init__.py,sha256=ZvNYPQyXWplaRQIxFR8CURcsnu_HRPXrwojF5nTmGd4,998 +transformers/models/dab_detr/__pycache__/__init__.cpython-310.pyc,, +transformers/models/dab_detr/__pycache__/configuration_dab_detr.cpython-310.pyc,, +transformers/models/dab_detr/__pycache__/modeling_dab_detr.cpython-310.pyc,, +transformers/models/dab_detr/configuration_dab_detr.py,sha256=fjcZVwy6FBw0bIF11yiAKppiNhdM4piE7P-rDoIPM90,11706 +transformers/models/dab_detr/modeling_dab_detr.py,sha256=hQIkFb9H5boJ3jsIHn5hvhDU6Jksw-MG7L8Rc6wbZwY,74317 +transformers/models/dac/__init__.py,sha256=UpwXPmSOQOwvbIvklM21-y5HKY7MEIInmTt65xMX6Hw,1029 +transformers/models/dac/__pycache__/__init__.cpython-310.pyc,, +transformers/models/dac/__pycache__/configuration_dac.cpython-310.pyc,, +transformers/models/dac/__pycache__/feature_extraction_dac.cpython-310.pyc,, +transformers/models/dac/__pycache__/modeling_dac.cpython-310.pyc,, +transformers/models/dac/configuration_dac.py,sha256=U2L-tEoIyDwjVqmYiomzvx4wpmNbFo-wn-cQXVMRSBY,4566 +transformers/models/dac/feature_extraction_dac.py,sha256=npYuHvnX-pyTvcfzxndRrLXgf-HLobCxF1Tt6-vhCpI,7911 +transformers/models/dac/modeling_dac.py,sha256=nycRu4erohiVg8MLuUggiyuDd9I_INl63wUn_qCmXSI,28980 +transformers/models/data2vec/__init__.py,sha256=BBiRVhmDgkquO28CdLOZNQztFSNQ9H-qP5wFYnI0NEc,1191 +transformers/models/data2vec/__pycache__/__init__.cpython-310.pyc,, +transformers/models/data2vec/__pycache__/configuration_data2vec_audio.cpython-310.pyc,, +transformers/models/data2vec/__pycache__/configuration_data2vec_text.cpython-310.pyc,, +transformers/models/data2vec/__pycache__/configuration_data2vec_vision.cpython-310.pyc,, +transformers/models/data2vec/__pycache__/modeling_data2vec_audio.cpython-310.pyc,, +transformers/models/data2vec/__pycache__/modeling_data2vec_text.cpython-310.pyc,, +transformers/models/data2vec/__pycache__/modeling_data2vec_vision.cpython-310.pyc,, +transformers/models/data2vec/__pycache__/modular_data2vec_audio.cpython-310.pyc,, +transformers/models/data2vec/__pycache__/modular_data2vec_text.cpython-310.pyc,, +transformers/models/data2vec/configuration_data2vec_audio.py,sha256=9km76IXHdakE-LGcSmRL6NuwRS7jieMRGfKB1MYevfc,16372 +transformers/models/data2vec/configuration_data2vec_text.py,sha256=jPhQS2d1AlOnnfLaKpJq6S6VXpTdf9kb5sxoyZ9c96c,6279 +transformers/models/data2vec/configuration_data2vec_vision.py,sha256=I9paAkhmabRr0UuoBrDQtrJ-FpJI6q8HNZnuXRChmuY,8656 +transformers/models/data2vec/modeling_data2vec_audio.py,sha256=Vt-5NRofZR7FL1nkV917lcU_ZAbn2SccrdRWuM1BmA0,55806 +transformers/models/data2vec/modeling_data2vec_text.py,sha256=XSsNk1qRMpjRn1eR80o6x3Wst6tEKBWT_-4Z9w2k2Ao,50766 +transformers/models/data2vec/modeling_data2vec_vision.py,sha256=SzdDUm_U8M3Ko-2NyMVm83VFx2Jgaxxq9pB7OWOghSY,53828 +transformers/models/data2vec/modular_data2vec_audio.py,sha256=9f7UwTtLQdTDQgY5er-WbBIMpJQ-t6aJhwRlxt00lYA,9673 +transformers/models/data2vec/modular_data2vec_text.py,sha256=28YoIAs7dfyr_GUtmD8kI2Jz_49aUNKi0Nyx2iHFAC4,23111 +transformers/models/dbrx/__init__.py,sha256=Kzn3gm0QHW9RKEmog_IfdCGam5TXSCzkOs_WHC43sgM,989 +transformers/models/dbrx/__pycache__/__init__.cpython-310.pyc,, +transformers/models/dbrx/__pycache__/configuration_dbrx.cpython-310.pyc,, +transformers/models/dbrx/__pycache__/modeling_dbrx.cpython-310.pyc,, +transformers/models/dbrx/__pycache__/modular_dbrx.cpython-310.pyc,, +transformers/models/dbrx/configuration_dbrx.py,sha256=jomeHhDvHRSn186SDdE-3Qp5UgHJNtyEPU2Yw5aiQfs,10261 +transformers/models/dbrx/modeling_dbrx.py,sha256=Hv5Y0_PxeSZZRCjUw9YhjTOTZs81qyt4XPYc2sXb1eU,32905 +transformers/models/dbrx/modular_dbrx.py,sha256=NlUtTubg1E4VVGDsK4b0t4JTznzmVcSCiVh8FNSM1cc,22540 +transformers/models/deberta/__init__.py,sha256=m87EmHGlh9isDhJ7-X7MlUa1cPhWtRYuqZPC3yGNE9I,1035 +transformers/models/deberta/__pycache__/__init__.cpython-310.pyc,, +transformers/models/deberta/__pycache__/configuration_deberta.cpython-310.pyc,, +transformers/models/deberta/__pycache__/modeling_deberta.cpython-310.pyc,, +transformers/models/deberta/__pycache__/tokenization_deberta.cpython-310.pyc,, +transformers/models/deberta/configuration_deberta.py,sha256=EzY9QZ-wOKwqLKr03ZWxmDQI6ceTSV8Lp1oKOE-sgc0,7383 +transformers/models/deberta/modeling_deberta.py,sha256=N__IL51LlMbFtO9fq8f0dVWO1BfJtW_8oEJ0GX9gk0k,47708 +transformers/models/deberta/tokenization_deberta.py,sha256=jNbgUuJtq-ydvv8AvtPDfC9CDErYTmBgKQxg7u3KEgI,7794 +transformers/models/deberta_v2/__init__.py,sha256=XIzvjcNgxx7TXV5zmtSG35QaaQMn86eQrHjijCcDM-M,1044 +transformers/models/deberta_v2/__pycache__/__init__.cpython-310.pyc,, +transformers/models/deberta_v2/__pycache__/configuration_deberta_v2.cpython-310.pyc,, +transformers/models/deberta_v2/__pycache__/modeling_deberta_v2.cpython-310.pyc,, +transformers/models/deberta_v2/__pycache__/tokenization_deberta_v2.cpython-310.pyc,, +transformers/models/deberta_v2/configuration_deberta_v2.py,sha256=SawGOL6295bJAee0NEx54ZlaYeBrCy60f5K9LzDphas,7455 +transformers/models/deberta_v2/modeling_deberta_v2.py,sha256=OoNZ4ySHZ2o0LyYulaABDPxJb5bgSJ2P5YjAIaIlWZQ,55656 +transformers/models/deberta_v2/tokenization_deberta_v2.py,sha256=X6QSEsBkJznuYssnr6iX7qTKPW5NGGpkjMn1J93JzJE,6634 +transformers/models/decision_transformer/__init__.py,sha256=8XAHnFrFv8IFz495cQLTeaAk2G1AVRT7roauVHCGoJs,1021 +transformers/models/decision_transformer/__pycache__/__init__.cpython-310.pyc,, +transformers/models/decision_transformer/__pycache__/configuration_decision_transformer.cpython-310.pyc,, +transformers/models/decision_transformer/__pycache__/modeling_decision_transformer.cpython-310.pyc,, +transformers/models/decision_transformer/configuration_decision_transformer.py,sha256=09DDdWKcxQQiw7Xr2-x8VdoaO17jLYGMaWNZfhNGYAc,7050 +transformers/models/decision_transformer/modeling_decision_transformer.py,sha256=rZUGYdRkaFSgyMcpEWyD60OmbPW7kwbA7hU_wLlVb10,30870 +transformers/models/deepseek_v2/__init__.py,sha256=cRpNT946KLnKXl4i2mGlImi9QLOe2a1ocnWNjBSbK68,1005 +transformers/models/deepseek_v2/__pycache__/__init__.cpython-310.pyc,, +transformers/models/deepseek_v2/__pycache__/configuration_deepseek_v2.cpython-310.pyc,, +transformers/models/deepseek_v2/__pycache__/modeling_deepseek_v2.cpython-310.pyc,, +transformers/models/deepseek_v2/__pycache__/modular_deepseek_v2.cpython-310.pyc,, +transformers/models/deepseek_v2/configuration_deepseek_v2.py,sha256=qUzPpZhMTgNojQCtyT03h4PyOg_fvZOxGeqVk02e55o,12464 +transformers/models/deepseek_v2/modeling_deepseek_v2.py,sha256=xymo5IbBWZvgdw9kRD2tb5r7Wel5wASzxOXWib13fEk,28038 +transformers/models/deepseek_v2/modular_deepseek_v2.py,sha256=6l2xQq6zi777zhPF6avKmZ5u6Yr9T9fyzhhX23QUnZ8,22053 +transformers/models/deepseek_v3/__init__.py,sha256=t-ejxAfULC_tUrUucNLt-x3hbTEIqUQp96m2DRFeaTg,1008 +transformers/models/deepseek_v3/__pycache__/__init__.cpython-310.pyc,, +transformers/models/deepseek_v3/__pycache__/configuration_deepseek_v3.cpython-310.pyc,, +transformers/models/deepseek_v3/__pycache__/modeling_deepseek_v3.cpython-310.pyc,, +transformers/models/deepseek_v3/__pycache__/modular_deepseek_v3.cpython-310.pyc,, +transformers/models/deepseek_v3/configuration_deepseek_v3.py,sha256=BamRSAra5s0YPdLhqjjiQ1uBR3qWSXcc_zfMag-wNmk,13014 +transformers/models/deepseek_v3/modeling_deepseek_v3.py,sha256=zaWlchlXTN9asIUs1EBX1lEy-5Ed30U64sr_0cEvxYY,32276 +transformers/models/deepseek_v3/modular_deepseek_v3.py,sha256=nXubznMj4TEETEAYXtKqEbhwzyMcu_BLPF0WQiXc_oI,14024 +transformers/models/deepseek_vl/__init__.py,sha256=ZjpL2NkjCM_tsGMz_fY7bOQ2HQwimj3RL4cocjrEtHI,1162 +transformers/models/deepseek_vl/__pycache__/__init__.cpython-310.pyc,, +transformers/models/deepseek_vl/__pycache__/configuration_deepseek_vl.cpython-310.pyc,, +transformers/models/deepseek_vl/__pycache__/image_processing_deepseek_vl.cpython-310.pyc,, +transformers/models/deepseek_vl/__pycache__/image_processing_deepseek_vl_fast.cpython-310.pyc,, +transformers/models/deepseek_vl/__pycache__/modeling_deepseek_vl.cpython-310.pyc,, +transformers/models/deepseek_vl/__pycache__/modular_deepseek_vl.cpython-310.pyc,, +transformers/models/deepseek_vl/__pycache__/processing_deepseek_vl.cpython-310.pyc,, +transformers/models/deepseek_vl/configuration_deepseek_vl.py,sha256=oW3DCnx2yadN_iVP5N5FbNNKQRGhI9CNhYRW_239jyI,4777 +transformers/models/deepseek_vl/image_processing_deepseek_vl.py,sha256=hxEk4GB7I3q-tnI7a_GtlI7em6Zp8kdJ0AJxIgqomRQ,21554 +transformers/models/deepseek_vl/image_processing_deepseek_vl_fast.py,sha256=lUnrkNw3fmUfPXFgfAPY-7L-CkVDQXlvH7_wlJaQLyo,7707 +transformers/models/deepseek_vl/modeling_deepseek_vl.py,sha256=uuTNw6otr8DOt15uzjx899J4Sr9F5aykEDmINHp_Zh0,15316 +transformers/models/deepseek_vl/modular_deepseek_vl.py,sha256=MyzeyFwZqib7J7UIS9kgdsIsJKO-hTHzDxh6_WrFZF4,10922 +transformers/models/deepseek_vl/processing_deepseek_vl.py,sha256=MBcQDEDZ5jHzIk2CjvU1ioTLGIrltFVKCogv3j1esFk,5389 +transformers/models/deepseek_vl_hybrid/__init__.py,sha256=FjSY1MYTEUP8BbAqIG2DZSAzmLh17w8aZr7pUkC_Gto,1257 +transformers/models/deepseek_vl_hybrid/__pycache__/__init__.cpython-310.pyc,, +transformers/models/deepseek_vl_hybrid/__pycache__/configuration_deepseek_vl_hybrid.cpython-310.pyc,, +transformers/models/deepseek_vl_hybrid/__pycache__/image_processing_deepseek_vl_hybrid.cpython-310.pyc,, +transformers/models/deepseek_vl_hybrid/__pycache__/image_processing_deepseek_vl_hybrid_fast.cpython-310.pyc,, +transformers/models/deepseek_vl_hybrid/__pycache__/modeling_deepseek_vl_hybrid.cpython-310.pyc,, +transformers/models/deepseek_vl_hybrid/__pycache__/modular_deepseek_vl_hybrid.cpython-310.pyc,, +transformers/models/deepseek_vl_hybrid/__pycache__/processing_deepseek_vl_hybrid.cpython-310.pyc,, +transformers/models/deepseek_vl_hybrid/configuration_deepseek_vl_hybrid.py,sha256=4Uo3V25PULUfhQXR93vYNhXQUhVGht5gYukv8HzVV_4,5686 +transformers/models/deepseek_vl_hybrid/image_processing_deepseek_vl_hybrid.py,sha256=GqDzYTNFdSkuO4kivOhVA2UpEuvUJYeAc6kCO6FsMME,28075 +transformers/models/deepseek_vl_hybrid/image_processing_deepseek_vl_hybrid_fast.py,sha256=aUVLO5j7zi5zrmx4_rKL7k4flmO0BV6PkobzSXzlxxE,12792 +transformers/models/deepseek_vl_hybrid/modeling_deepseek_vl_hybrid.py,sha256=dsNscx4FZRxlPYnMQ17IumJNuddnJsasGpeNcobQtfg,25320 +transformers/models/deepseek_vl_hybrid/modular_deepseek_vl_hybrid.py,sha256=3WlOXUYlLunuwTk69NFotu7ZwDYXT-Y9TKTTUPv0k8E,49619 +transformers/models/deepseek_vl_hybrid/processing_deepseek_vl_hybrid.py,sha256=USx2UqYc0Ocp1cRNrFrQratD8wm67iOGSHeaI00zLt4,5552 +transformers/models/deformable_detr/__init__.py,sha256=_ae-sABBY17hOT28SN_d0GLeRVjya0W4aqniH8u8Bcw,1176 +transformers/models/deformable_detr/__pycache__/__init__.cpython-310.pyc,, +transformers/models/deformable_detr/__pycache__/configuration_deformable_detr.cpython-310.pyc,, +transformers/models/deformable_detr/__pycache__/image_processing_deformable_detr.cpython-310.pyc,, +transformers/models/deformable_detr/__pycache__/image_processing_deformable_detr_fast.cpython-310.pyc,, +transformers/models/deformable_detr/__pycache__/modeling_deformable_detr.cpython-310.pyc,, +transformers/models/deformable_detr/__pycache__/modular_deformable_detr.cpython-310.pyc,, +transformers/models/deformable_detr/configuration_deformable_detr.py,sha256=Y6MO1uFuL9qxS9ITvPV6zKl1dQBEQno_G_uqVfpt5TQ,12669 +transformers/models/deformable_detr/image_processing_deformable_detr.py,sha256=j9RQ8K40wuqfc3snUrddPXS952MZLp1fCqu4SYqRbAk,67106 +transformers/models/deformable_detr/image_processing_deformable_detr_fast.py,sha256=E4fbnaaGLUNMo45D_5sLAWn0CN6Ckn_r6Z6iW8im3DM,29150 +transformers/models/deformable_detr/modeling_deformable_detr.py,sha256=eyjRNO-laSa08zrfx0ZvXMp2Ux4PRfrMDPVWsmSCbZY,78855 +transformers/models/deformable_detr/modular_deformable_detr.py,sha256=3BoiLJ9OA-bHQrQaxNgsJFU5Mu2YnL-b1MdEC8T-7To,68936 +transformers/models/deit/__init__.py,sha256=22WX8RQ-IVaOQsYrJ4D8ZQPZ_OHFGJf9dZ_6F-mRHAg,1119 +transformers/models/deit/__pycache__/__init__.cpython-310.pyc,, +transformers/models/deit/__pycache__/configuration_deit.cpython-310.pyc,, +transformers/models/deit/__pycache__/image_processing_deit.cpython-310.pyc,, +transformers/models/deit/__pycache__/image_processing_deit_fast.cpython-310.pyc,, +transformers/models/deit/__pycache__/modeling_deit.cpython-310.pyc,, +transformers/models/deit/configuration_deit.py,sha256=7OeJSbdqJw-P8AqBfYbZrgTb_RlkmAxH2ExSt7QKAkA,5624 +transformers/models/deit/image_processing_deit.py,sha256=y-N0WSuoiE5DK6T_LtkSiE0je1njU8_GDvgVXH7OOBw,14925 +transformers/models/deit/image_processing_deit_fast.py,sha256=f9sMcuPByCWA_ZDVb-qaucE-kQk769oP4iA4fESKhus,1384 +transformers/models/deit/modeling_deit.py,sha256=WddVqPwax70zVa2nYWutxR0QJqjL0ziB97O6wXBOwko,30280 +transformers/models/deprecated/__init__.py,sha256=cBbCmNwJS_K7Qxng1In7TGSmzj61crBAhb6mN_NoqDI,988 +transformers/models/deprecated/__pycache__/__init__.cpython-310.pyc,, +transformers/models/depth_anything/__init__.py,sha256=Jbd8LXt-fU3_cTF7jBrkBBw-Kzscv6o7O0YiZy0R8-A,1009 +transformers/models/depth_anything/__pycache__/__init__.cpython-310.pyc,, +transformers/models/depth_anything/__pycache__/configuration_depth_anything.cpython-310.pyc,, +transformers/models/depth_anything/__pycache__/modeling_depth_anything.cpython-310.pyc,, +transformers/models/depth_anything/configuration_depth_anything.py,sha256=3ZBbBFvT_vyt-B-hdrv17Ke6lAYKSAVfydm4fPSxzRo,5531 +transformers/models/depth_anything/modeling_depth_anything.py,sha256=bNyDEj_1-R3rQv0ZnL_nVNIsj8Qi-fc6Qwv_ZH8mKbk,16130 +transformers/models/depth_pro/__init__.py,sha256=5R4N4IVUQuK8bCFtg9qGvJFceJaHXNj4HdCWkcsyELc,1096 +transformers/models/depth_pro/__pycache__/__init__.cpython-310.pyc,, +transformers/models/depth_pro/__pycache__/configuration_depth_pro.cpython-310.pyc,, +transformers/models/depth_pro/__pycache__/image_processing_depth_pro.cpython-310.pyc,, +transformers/models/depth_pro/__pycache__/image_processing_depth_pro_fast.cpython-310.pyc,, +transformers/models/depth_pro/__pycache__/modeling_depth_pro.cpython-310.pyc,, +transformers/models/depth_pro/configuration_depth_pro.py,sha256=XzLH10lsxx5iw7zk-sNidYASQQxSucoaeVSduO92WyM,10660 +transformers/models/depth_pro/image_processing_depth_pro.py,sha256=ImE0AuaF8tuRmaJKyRxH7hSWJVvSrP6l44w0fd-tJ2o,18546 +transformers/models/depth_pro/image_processing_depth_pro_fast.py,sha256=1nCyOa139QDSqPu57iCil3kcv7NKau8fPQUJ_IlAxh0,6532 +transformers/models/depth_pro/modeling_depth_pro.py,sha256=a21KoslZNzT8EzJiFiAfpF_S-aVY3H4zCm_BPejOQCI,42507 +transformers/models/detr/__init__.py,sha256=YEWZnoCCgWt4KZNfbSi-v4KNDOJT2-ii2sxanyVDkvY,1120 +transformers/models/detr/__pycache__/__init__.cpython-310.pyc,, +transformers/models/detr/__pycache__/configuration_detr.cpython-310.pyc,, +transformers/models/detr/__pycache__/image_processing_detr.cpython-310.pyc,, +transformers/models/detr/__pycache__/image_processing_detr_fast.cpython-310.pyc,, +transformers/models/detr/__pycache__/modeling_detr.cpython-310.pyc,, +transformers/models/detr/configuration_detr.py,sha256=seCsIsaVuD4zXrnPkQsCEO2W24m7kxBG4yGyBeoaJH0,10442 +transformers/models/detr/image_processing_detr.py,sha256=SYvJ5RrkQffGG78ciqK3ZQXYvghnxTNnBQAq7LbVwyc,76482 +transformers/models/detr/image_processing_detr_fast.py,sha256=rF1XNhdwqNRuKdA1zs9faB-7Q7NbzbWkvX56ZGTQkYA,40187 +transformers/models/detr/modeling_detr.py,sha256=L0w3kiq_HWDRNZmktRyqwFKJMOtB3lVoAZ4VKTeBUTE,73626 +transformers/models/dia/__init__.py,sha256=fvBcwJ7FAFDO6RNyUUMGrdSlUtowciNo3YYv7R2Qz1c,1133 +transformers/models/dia/__pycache__/__init__.cpython-310.pyc,, +transformers/models/dia/__pycache__/configuration_dia.cpython-310.pyc,, +transformers/models/dia/__pycache__/feature_extraction_dia.cpython-310.pyc,, +transformers/models/dia/__pycache__/generation_dia.cpython-310.pyc,, +transformers/models/dia/__pycache__/modeling_dia.cpython-310.pyc,, +transformers/models/dia/__pycache__/modular_dia.cpython-310.pyc,, +transformers/models/dia/__pycache__/processing_dia.cpython-310.pyc,, +transformers/models/dia/__pycache__/tokenization_dia.cpython-310.pyc,, +transformers/models/dia/configuration_dia.py,sha256=Swh0mNqV1B8fsxLnxQahr6qTsbMTniejhTIkfMeKLvk,16037 +transformers/models/dia/feature_extraction_dia.py,sha256=6-jSEtsGgLZx8gbI9MC_MVbTdfyz6fnpc6olNxPkcD8,8353 +transformers/models/dia/generation_dia.py,sha256=nzF61cxnD910FkSRKR6zoqu0r8MxPy10THfa0WIzor8,21486 +transformers/models/dia/modeling_dia.py,sha256=WMofJsgoG5ZFyNvx_XgtUh02yw1YQYUiJSHZF6dm2KE,40523 +transformers/models/dia/modular_dia.py,sha256=zJ1hgG2OaX-tpqdHbJysbsCo15Tr6QbMBVR6uLG7a4w,30182 +transformers/models/dia/processing_dia.py,sha256=7lDMN1gjv-csnjqOUUMT9z5buVZV9jACu5aubnlixVQ,20779 +transformers/models/dia/tokenization_dia.py,sha256=lWhjp7RgJ5Ok8TErIHH12dMHzbRPt9Q_m5_AgwUP5JY,4489 +transformers/models/dialogpt/__init__.py,sha256=47DEQpj8HBSa-_TImW-5JCeuQeRkm5NMpJWZG3hSuFU,0 +transformers/models/dialogpt/__pycache__/__init__.cpython-310.pyc,, +transformers/models/diffllama/__init__.py,sha256=Yosk5eQ82PblntLff-bL3pfJZ-AVKp5jbQK5R2SLVc8,1004 +transformers/models/diffllama/__pycache__/__init__.cpython-310.pyc,, +transformers/models/diffllama/__pycache__/configuration_diffllama.cpython-310.pyc,, +transformers/models/diffllama/__pycache__/modeling_diffllama.cpython-310.pyc,, +transformers/models/diffllama/__pycache__/modular_diffllama.cpython-310.pyc,, +transformers/models/diffllama/configuration_diffllama.py,sha256=XTiEO3lP4HDImFNGPybRaCDC9yjcZpVj4bSPjFn9ht0,7812 +transformers/models/diffllama/modeling_diffllama.py,sha256=86y5Cegle2KcsrgpAZnvpAtZ2HqNZJI40qR2P5gZJ7k,35108 +transformers/models/diffllama/modular_diffllama.py,sha256=pHiUWgmi83f0xGMJOkgLNGUJZSonWbFHlFPoy4sdc80,19073 +transformers/models/dinat/__init__.py,sha256=N0HykajUSY5KsvPQNUxc8jAuuJntmDJ-Dz8Qa8_sJ9E,991 +transformers/models/dinat/__pycache__/__init__.cpython-310.pyc,, +transformers/models/dinat/__pycache__/configuration_dinat.cpython-310.pyc,, +transformers/models/dinat/__pycache__/modeling_dinat.cpython-310.pyc,, +transformers/models/dinat/configuration_dinat.py,sha256=rtRc6yrNLl1NBCp1iHtnIP2FiJnrhoBbAyvoEfusf_8,7196 +transformers/models/dinat/modeling_dinat.py,sha256=bTLuaSsMNTz5fAD-3TpcyyeUghYfkHpBxFabJve0XVs,31396 +transformers/models/dinov2/__init__.py,sha256=OvrAMlhyPaMvvE5W2x3hxQ6EjkPYZgesizI_jOC5K3E,993 +transformers/models/dinov2/__pycache__/__init__.cpython-310.pyc,, +transformers/models/dinov2/__pycache__/configuration_dinov2.cpython-310.pyc,, +transformers/models/dinov2/__pycache__/modeling_dinov2.cpython-310.pyc,, +transformers/models/dinov2/configuration_dinov2.py,sha256=AMMGX-4R0xwnx7nBlbpCUhU8PfR9yAg6cxBDeELrhsI,7574 +transformers/models/dinov2/modeling_dinov2.py,sha256=GIzisMmp4WMcOhUreCHklVBYTk9W38Syw54dRL9GcDw,25325 +transformers/models/dinov2_with_registers/__init__.py,sha256=s0cefgSRnlIVcdZYV0qz3Q9X3IEChU7mkGbbnr2IH6E,1023 +transformers/models/dinov2_with_registers/__pycache__/__init__.cpython-310.pyc,, +transformers/models/dinov2_with_registers/__pycache__/configuration_dinov2_with_registers.cpython-310.pyc,, +transformers/models/dinov2_with_registers/__pycache__/modeling_dinov2_with_registers.cpython-310.pyc,, +transformers/models/dinov2_with_registers/__pycache__/modular_dinov2_with_registers.cpython-310.pyc,, +transformers/models/dinov2_with_registers/configuration_dinov2_with_registers.py,sha256=qJQexsJEHcqK1Wiof71llu2OGa41COKI2yVyg9DrAKM,8474 +transformers/models/dinov2_with_registers/modeling_dinov2_with_registers.py,sha256=Dq_ISTP0hkH03go2DG3KBUu58xi6J7IOVfLbsUwHXCQ,27619 +transformers/models/dinov2_with_registers/modular_dinov2_with_registers.py,sha256=cRdtE-es0rLtPz7CIP0Bb_89HG4YRPaJtrwhcKsCwTA,18830 +transformers/models/dinov3_convnext/__init__.py,sha256=8VOE7Jnq3g2JBuwkVcsFoZEerdZF5dn2p5XZ26BMRY4,1011 +transformers/models/dinov3_convnext/__pycache__/__init__.cpython-310.pyc,, +transformers/models/dinov3_convnext/__pycache__/configuration_dinov3_convnext.cpython-310.pyc,, +transformers/models/dinov3_convnext/__pycache__/modeling_dinov3_convnext.cpython-310.pyc,, +transformers/models/dinov3_convnext/configuration_dinov3_convnext.py,sha256=_tvzf7vZq4wtpryOp3tvlEzCKwFg2bKp2mI-tOchnOM,5494 +transformers/models/dinov3_convnext/modeling_dinov3_convnext.py,sha256=BX4ptxOF7uzkgMvIOz-d6j8H41OXSaf8hYjTMaSmp2c,11665 +transformers/models/dinov3_vit/__init__.py,sha256=DYSqKAAuJCZAhQyu7pcechuSR025KnzcKNtJIafTq1E,1053 +transformers/models/dinov3_vit/__pycache__/__init__.cpython-310.pyc,, +transformers/models/dinov3_vit/__pycache__/configuration_dinov3_vit.cpython-310.pyc,, +transformers/models/dinov3_vit/__pycache__/image_processing_dinov3_vit_fast.cpython-310.pyc,, +transformers/models/dinov3_vit/__pycache__/modeling_dinov3_vit.cpython-310.pyc,, +transformers/models/dinov3_vit/__pycache__/modular_dinov3_vit.cpython-310.pyc,, +transformers/models/dinov3_vit/configuration_dinov3_vit.py,sha256=JBfI2Amz3X6Ui6R8X3593J3ePBbRt5vP0eetzPEUf38,8922 +transformers/models/dinov3_vit/image_processing_dinov3_vit_fast.py,sha256=UTZsVUraoQkqdbJD3d6uIXktU1pL10tAsYmc4lqpgho,3785 +transformers/models/dinov3_vit/modeling_dinov3_vit.py,sha256=8ej9_lhvaRniKbcrlTigiK9QCmfGWQHIjKhcp5VtwL0,24523 +transformers/models/dinov3_vit/modular_dinov3_vit.py,sha256=btlOJ7xLGQj4qltmydRYWaebtJVlVsqZHYSEN6HpM40,19792 +transformers/models/distilbert/__init__.py,sha256=g2DClKY8TLVEIIc78BEBK1nFt50A0aVoL2o3OVuF_yE,1087 +transformers/models/distilbert/__pycache__/__init__.cpython-310.pyc,, +transformers/models/distilbert/__pycache__/configuration_distilbert.cpython-310.pyc,, +transformers/models/distilbert/__pycache__/modeling_distilbert.cpython-310.pyc,, +transformers/models/distilbert/__pycache__/tokenization_distilbert.cpython-310.pyc,, +transformers/models/distilbert/configuration_distilbert.py,sha256=Rk-RpZhopJaxGI-bf0SFzbN4U6e1-kWoqup5nCLF_wg,5645 +transformers/models/distilbert/modeling_distilbert.py,sha256=P60z4xDcBIWn0tLy-WZ-KqQM1gW89KEYl59g7rQI2yU,40033 +transformers/models/distilbert/tokenization_distilbert.py,sha256=BeXGmu3Y-cDILXqWBBWipyXXTluNyemzkquubE2lhFs,1716 +transformers/models/dit/__init__.py,sha256=47DEQpj8HBSa-_TImW-5JCeuQeRkm5NMpJWZG3hSuFU,0 +transformers/models/dit/__pycache__/__init__.cpython-310.pyc,, +transformers/models/doge/__init__.py,sha256=VtPJpOlqDfo3mV2yzOowL6LTgQkm61JpmgaSmQX18t4,1009 +transformers/models/doge/__pycache__/__init__.cpython-310.pyc,, +transformers/models/doge/__pycache__/configuration_doge.cpython-310.pyc,, +transformers/models/doge/__pycache__/modeling_doge.cpython-310.pyc,, +transformers/models/doge/__pycache__/modular_doge.cpython-310.pyc,, +transformers/models/doge/configuration_doge.py,sha256=R7BarJ0XvOZxUTIDRVkFrnd8nwQlayItqUCluudxkcw,11251 +transformers/models/doge/modeling_doge.py,sha256=1pj508z4ZETHVkgAaMxlZ0pnGOICT1Af0HMArsB-kMc,37130 +transformers/models/doge/modular_doge.py,sha256=7ayRpBKtMuDCrCr2KjANYC5Zhq7deTyoTCoee5usotc,34223 +transformers/models/donut/__init__.py,sha256=O1JOQtPxtjcxSfWgC_PUZkmfvcKzjPgNAakujNra1PA,1170 +transformers/models/donut/__pycache__/__init__.cpython-310.pyc,, +transformers/models/donut/__pycache__/configuration_donut_swin.cpython-310.pyc,, +transformers/models/donut/__pycache__/image_processing_donut.cpython-310.pyc,, +transformers/models/donut/__pycache__/image_processing_donut_fast.cpython-310.pyc,, +transformers/models/donut/__pycache__/modeling_donut_swin.cpython-310.pyc,, +transformers/models/donut/__pycache__/processing_donut.cpython-310.pyc,, +transformers/models/donut/configuration_donut_swin.py,sha256=SCjrLe7uGr7eOrIMW8M5PAK0Ei-hKo9ayT1fDPE-SIc,5770 +transformers/models/donut/image_processing_donut.py,sha256=FBr0kdbC5rbPk54m0720vksabRuBNIk32MZF-Naoz00,22228 +transformers/models/donut/image_processing_donut_fast.py,sha256=kSUh5i3UTCMvfwsTVXA5csUwrcBiUbSF-1yKbU0ZvuM,9177 +transformers/models/donut/modeling_donut_swin.py,sha256=Ou_ndzqYJ6cXTJa-BghF4UjgY5jhnXRtzofAyVlF8H0,42263 +transformers/models/donut/processing_donut.py,sha256=lBJU3ezF9anLjKfhib448PCzwZ8q1WDOLH-fAdlr6dk,5287 +transformers/models/dots1/__init__.py,sha256=A2jXARtNWOrbWAW2SIrsvvydm2_2keRyUBbNEz0By-I,991 +transformers/models/dots1/__pycache__/__init__.cpython-310.pyc,, +transformers/models/dots1/__pycache__/configuration_dots1.cpython-310.pyc,, +transformers/models/dots1/__pycache__/modeling_dots1.cpython-310.pyc,, +transformers/models/dots1/__pycache__/modular_dots1.cpython-310.pyc,, +transformers/models/dots1/configuration_dots1.py,sha256=wDom52PssYSQTsjRyk_xJil3dJaBB6WUFla_Nrw4AW4,10915 +transformers/models/dots1/modeling_dots1.py,sha256=8d8fUExhYTa4z7lNF_MVag2fm6uDACpG3tQ9b3q-F7A,29464 +transformers/models/dots1/modular_dots1.py,sha256=Zx07vgiM2UmQbh4R9669e0sUqsjglaNVZw3a86tcKlo,4587 +transformers/models/dpr/__init__.py,sha256=YLpIDXI8WhGlQM_ED82JpDIdk4k0C8HKgw5Qigt5NkY,1064 +transformers/models/dpr/__pycache__/__init__.cpython-310.pyc,, +transformers/models/dpr/__pycache__/configuration_dpr.cpython-310.pyc,, +transformers/models/dpr/__pycache__/modeling_dpr.cpython-310.pyc,, +transformers/models/dpr/__pycache__/tokenization_dpr.cpython-310.pyc,, +transformers/models/dpr/__pycache__/tokenization_dpr_fast.cpython-310.pyc,, +transformers/models/dpr/configuration_dpr.py,sha256=GFtTbX6CHzNaHL3WrttQkBgmPDxarQ02_EtHXT8ZJfw,6489 +transformers/models/dpr/modeling_dpr.py,sha256=B_uY-YTmr8hKVKCE64gokoq4tqEnqw239d_zDN79EKY,21848 +transformers/models/dpr/tokenization_dpr.py,sha256=7cfukFJ146eWUSK2euLdUWbZeVjpltfEapqB6aliLGY,16128 +transformers/models/dpr/tokenization_dpr_fast.py,sha256=ObKSKMda0tBWvBA1uNjQlZMtNK0EJ3b7qUkXDRhgd38,16020 +transformers/models/dpt/__init__.py,sha256=7i4wNFCo8NTFsJQi7TO9u0VGxpZ8xg1_QNvD862jNk4,1114 +transformers/models/dpt/__pycache__/__init__.cpython-310.pyc,, +transformers/models/dpt/__pycache__/configuration_dpt.cpython-310.pyc,, +transformers/models/dpt/__pycache__/image_processing_dpt.cpython-310.pyc,, +transformers/models/dpt/__pycache__/image_processing_dpt_fast.cpython-310.pyc,, +transformers/models/dpt/__pycache__/modeling_dpt.cpython-310.pyc,, +transformers/models/dpt/__pycache__/modular_dpt.cpython-310.pyc,, +transformers/models/dpt/configuration_dpt.py,sha256=_lJYB-ch2xGsaYjos9M8IgSxqKAlKFuePx7DMfDG6q8,11668 +transformers/models/dpt/image_processing_dpt.py,sha256=3gTA-CC5_eBXDQKc8Ne8aH3XmZMJnRj8fUgRlQbPo9U,32105 +transformers/models/dpt/image_processing_dpt_fast.py,sha256=y59Qn0SSBcK7wEjNXnTFUoIrxZxZ0wDMw4wB5o2851Y,15628 +transformers/models/dpt/modeling_dpt.py,sha256=0OvrMDjbKNq8jbhaQSlGmPEr5QlPbOJTepoIHsHrrE4,48306 +transformers/models/dpt/modular_dpt.py,sha256=ps6WtygQYgCG-fR4nIp1SsTbtf_72L4F_3Rom8S7hZY,10479 +transformers/models/edgetam/__init__.py,sha256=oGzMZGNhQp2fv5UQEYcLdYLUIRQEnn3_vucmlOvmM_o,995 +transformers/models/edgetam/__pycache__/__init__.cpython-310.pyc,, +transformers/models/edgetam/__pycache__/configuration_edgetam.cpython-310.pyc,, +transformers/models/edgetam/__pycache__/modeling_edgetam.cpython-310.pyc,, +transformers/models/edgetam/__pycache__/modular_edgetam.cpython-310.pyc,, +transformers/models/edgetam/configuration_edgetam.py,sha256=isGXAI-MEswVuIl1jN6v9Qhezm2xqxw0rD8qoRr3qX8,15752 +transformers/models/edgetam/modeling_edgetam.py,sha256=5YKRi6qEA6EuK14hnD_Vi_govBYQ9XN6FckRpkvQlp0,58870 +transformers/models/edgetam/modular_edgetam.py,sha256=DN8bEi_CH4EQcoA_TxRBvoES6anCZsO0AxEpk-eiEMI,12139 +transformers/models/edgetam_video/__init__.py,sha256=aNgAv9cdlvg857E879-BnK4HwZ-LuC1LC2fw8hOPtFU,1008 +transformers/models/edgetam_video/__pycache__/__init__.cpython-310.pyc,, +transformers/models/edgetam_video/__pycache__/configuration_edgetam_video.cpython-310.pyc,, +transformers/models/edgetam_video/__pycache__/modeling_edgetam_video.cpython-310.pyc,, +transformers/models/edgetam_video/__pycache__/modular_edgetam_video.cpython-310.pyc,, +transformers/models/edgetam_video/configuration_edgetam_video.py,sha256=YmXZfXvSHOuT2iNmoqkn62mmCYFGNM1I6IGoqAkLjyI,23952 +transformers/models/edgetam_video/modeling_edgetam_video.py,sha256=Ajau-Zd8sIl1xZrLz2xhkzXkVRsHxvZpTNTgAzD_ZkM,146530 +transformers/models/edgetam_video/modular_edgetam_video.py,sha256=VyOA8dMAkhAyELT2C_xuLPqHUvuj77--5mQ8k74uV_4,71115 +transformers/models/efficientloftr/__init__.py,sha256=tG2whk3HBxtW2jyKIXiiHuLxzHhaGo8YmfxgZbX-57k,1116 +transformers/models/efficientloftr/__pycache__/__init__.cpython-310.pyc,, +transformers/models/efficientloftr/__pycache__/configuration_efficientloftr.cpython-310.pyc,, +transformers/models/efficientloftr/__pycache__/image_processing_efficientloftr.cpython-310.pyc,, +transformers/models/efficientloftr/__pycache__/image_processing_efficientloftr_fast.cpython-310.pyc,, +transformers/models/efficientloftr/__pycache__/modeling_efficientloftr.cpython-310.pyc,, +transformers/models/efficientloftr/__pycache__/modular_efficientloftr.cpython-310.pyc,, +transformers/models/efficientloftr/configuration_efficientloftr.py,sha256=mxRxEWagKcvL1eTY_zz3I4LeL4VMhwj5o9cmkHmxtbo,9406 +transformers/models/efficientloftr/image_processing_efficientloftr.py,sha256=arxSJJ0BH7IjA4hbA6HBmXT3H17UvmAW5pnB6YM1p6E,21509 +transformers/models/efficientloftr/image_processing_efficientloftr_fast.py,sha256=wi7p8ESzwEdyi9tsTbSrRyLEzLLSYruPzH1pUS_-HTw,12433 +transformers/models/efficientloftr/modeling_efficientloftr.py,sha256=h8KFcfzfW5BucRke4rX6voluLdwBHrwyPyWSmpsQ5Vw,61444 +transformers/models/efficientloftr/modular_efficientloftr.py,sha256=F0rcfYhynItNCvyjMhLazwuocF2UWpjKgGFhMXTNN6E,3263 +transformers/models/efficientnet/__init__.py,sha256=0wxLCBxWBCh8uj4nH1syYJ76kRvUlMS6EUN5E2L2Qwc,1108 +transformers/models/efficientnet/__pycache__/__init__.cpython-310.pyc,, +transformers/models/efficientnet/__pycache__/configuration_efficientnet.cpython-310.pyc,, +transformers/models/efficientnet/__pycache__/image_processing_efficientnet.cpython-310.pyc,, +transformers/models/efficientnet/__pycache__/image_processing_efficientnet_fast.cpython-310.pyc,, +transformers/models/efficientnet/__pycache__/modeling_efficientnet.cpython-310.pyc,, +transformers/models/efficientnet/configuration_efficientnet.py,sha256=EnjJHPh_xZDW0jbYWL6HOg1l1VVBTBVu9LLXB19t3pA,7076 +transformers/models/efficientnet/image_processing_efficientnet.py,sha256=eD8RII0RaBMkKZBe3YL6yGqcdj3b3LicuPt2HIcfTm4,18470 +transformers/models/efficientnet/image_processing_efficientnet_fast.py,sha256=_lS_kf94Y8Q54507kM7592sgtrjtEHkqk0JtSri6F7Q,7180 +transformers/models/efficientnet/modeling_efficientnet.py,sha256=aeauNMai59TDV9rLPLyVOAGrqhVOnIG7brKG2C_rW1c,20366 +transformers/models/electra/__init__.py,sha256=foRaRrXexLO6dUKs4iPX0nc27V1AuGrUur66Ih64Zk4,1070 +transformers/models/electra/__pycache__/__init__.cpython-310.pyc,, +transformers/models/electra/__pycache__/configuration_electra.cpython-310.pyc,, +transformers/models/electra/__pycache__/modeling_electra.cpython-310.pyc,, +transformers/models/electra/configuration_electra.py,sha256=aD8-jenY8A4q_F5iYvu0vHWeTl-Zry7sm9EZ0VvQ9O4,8088 +transformers/models/electra/modeling_electra.py,sha256=O4IP91Op_paAy4NWF_CJQkyElP2_K0jr8ST7ol3fAjI,58467 +transformers/models/emu3/__init__.py,sha256=VEBLADqeToacty2xd3Zu0F_fLQRxvhfiKPkuB9jwcFM,1070 +transformers/models/emu3/__pycache__/__init__.cpython-310.pyc,, +transformers/models/emu3/__pycache__/configuration_emu3.cpython-310.pyc,, +transformers/models/emu3/__pycache__/image_processing_emu3.cpython-310.pyc,, +transformers/models/emu3/__pycache__/modeling_emu3.cpython-310.pyc,, +transformers/models/emu3/__pycache__/modular_emu3.cpython-310.pyc,, +transformers/models/emu3/__pycache__/processing_emu3.cpython-310.pyc,, +transformers/models/emu3/configuration_emu3.py,sha256=yONcECjqiD25t1cbMuZzoTDGlmuIZxWUswf0Htzk4_o,13481 +transformers/models/emu3/image_processing_emu3.py,sha256=XO61pIkkjE502c49V6TRYV-feKOg5EB1IAH8_9IWLxc,27118 +transformers/models/emu3/modeling_emu3.py,sha256=UlxjzQNzsvq8lPUgDggiaPTMtIY4I_DE29iUkTCiUGU,67692 +transformers/models/emu3/modular_emu3.py,sha256=oPLuv6hXqExcNIs40LCCia9UWoxxfzWAWYPf-NwjIyE,47874 +transformers/models/emu3/processing_emu3.py,sha256=C6s-VHhfwmNUvT-FvhG06AETbF2jUObSkXVSWUqtTI0,11488 +transformers/models/encodec/__init__.py,sha256=QbO9yEfCaRwYKbK0vvmwKMbqRAToyos-HTHhRmf7n5s,1041 +transformers/models/encodec/__pycache__/__init__.cpython-310.pyc,, +transformers/models/encodec/__pycache__/configuration_encodec.cpython-310.pyc,, +transformers/models/encodec/__pycache__/feature_extraction_encodec.cpython-310.pyc,, +transformers/models/encodec/__pycache__/modeling_encodec.cpython-310.pyc,, +transformers/models/encodec/configuration_encodec.py,sha256=Jpd4Ct4dmoDnT10dr6YSM8dd2-dmB6MQnjIckd1zLbc,8656 +transformers/models/encodec/feature_extraction_encodec.py,sha256=sVGWrleWmP3YZodQeRg6FU3mlLWPxjc-m4vK-qI_E0g,9784 +transformers/models/encodec/modeling_encodec.py,sha256=nahm0gi9hHJpuLysOruB4Sr8qwIcpuWagZKyZbnJXJg,35224 +transformers/models/encoder_decoder/__init__.py,sha256=NRHrw_Gq2RpeLthXifL3JiePYtsXaetRuhXbVkQtQUs,1011 +transformers/models/encoder_decoder/__pycache__/__init__.cpython-310.pyc,, +transformers/models/encoder_decoder/__pycache__/configuration_encoder_decoder.cpython-310.pyc,, +transformers/models/encoder_decoder/__pycache__/modeling_encoder_decoder.cpython-310.pyc,, +transformers/models/encoder_decoder/configuration_encoder_decoder.py,sha256=Bo7uLsyIUyHV_1rdhPt90JYJ9YFi3PTEwrfp-GB8QG0,5007 +transformers/models/encoder_decoder/modeling_encoder_decoder.py,sha256=yejO8tVAJSlX7HxNBxCE2yieuuX83Qlo9sgoPLu-ARQ,22527 +transformers/models/eomt/__init__.py,sha256=yXVhFSLXI_umGHqTtRHHaTevf4KwrA9LOldvY7DfuFk,1076 +transformers/models/eomt/__pycache__/__init__.cpython-310.pyc,, +transformers/models/eomt/__pycache__/configuration_eomt.cpython-310.pyc,, +transformers/models/eomt/__pycache__/image_processing_eomt.cpython-310.pyc,, +transformers/models/eomt/__pycache__/image_processing_eomt_fast.cpython-310.pyc,, +transformers/models/eomt/__pycache__/modeling_eomt.cpython-310.pyc,, +transformers/models/eomt/__pycache__/modular_eomt.cpython-310.pyc,, +transformers/models/eomt/configuration_eomt.py,sha256=dhMJZnQ9sog1ojOFkB2ZY0jRd1tu-KKt2g6-mAmHy50,8053 +transformers/models/eomt/image_processing_eomt.py,sha256=IHFmgkExd9bgl-bsElRElRrNIHAcmo5CEtIJSYcaW48,40587 +transformers/models/eomt/image_processing_eomt_fast.py,sha256=LHYH8ETxhQDRro9yua-ZD987G9gADS-FmurOl1q97IQ,22466 +transformers/models/eomt/modeling_eomt.py,sha256=-alkhX10-SSFM0WdnTYLeouKznWxbIg7O2j7ATFdi0Y,54712 +transformers/models/eomt/modular_eomt.py,sha256=A90eBIV-1kdkKJg8SYXpbvbGc4_2TLCzDNlTOQX1xmM,25946 +transformers/models/eomt_dinov3/__init__.py,sha256=Z1U6ubtfNVB84kWYgRZX1bZy1vrJCVHKB_vfU9H1TwU,1004 +transformers/models/eomt_dinov3/__pycache__/__init__.cpython-310.pyc,, +transformers/models/eomt_dinov3/__pycache__/configuration_eomt_dinov3.cpython-310.pyc,, +transformers/models/eomt_dinov3/__pycache__/modeling_eomt_dinov3.cpython-310.pyc,, +transformers/models/eomt_dinov3/__pycache__/modular_eomt_dinov3.cpython-310.pyc,, +transformers/models/eomt_dinov3/configuration_eomt_dinov3.py,sha256=E9chM2Iit8CSumZuXQv_w1T4hzaH17prUIbjkABUT54,10427 +transformers/models/eomt_dinov3/modeling_eomt_dinov3.py,sha256=Rghe3KeQWzBxKbyKA2a3rOKz-JlJlsEWvI-TcpoK6vs,61174 +transformers/models/eomt_dinov3/modular_eomt_dinov3.py,sha256=2LaxUnyBrOn8Wk78IEZCaygwvntZqgdhtX3Skn24Orw,19880 +transformers/models/ernie/__init__.py,sha256=TyzaXpzGwu-WqsIn1tavDqa7BCV9X-mPho4JDa9gk0I,991 +transformers/models/ernie/__pycache__/__init__.cpython-310.pyc,, +transformers/models/ernie/__pycache__/configuration_ernie.cpython-310.pyc,, +transformers/models/ernie/__pycache__/modeling_ernie.cpython-310.pyc,, +transformers/models/ernie/__pycache__/modular_ernie.cpython-310.pyc,, +transformers/models/ernie/configuration_ernie.py,sha256=j9SWHIagDdk4tivnQ-ON-lR56seMDXAP02qu-dRFWbM,7247 +transformers/models/ernie/modeling_ernie.py,sha256=Ou7nh40MNLgZ7M-wSUaEVnZa45fEkuKYwK_7Rh4nSYQ,64351 +transformers/models/ernie/modular_ernie.py,sha256=enpFHZymNzM1xkGvcAYC2JhvCeeyxTIWThfClgDDNU4,38546 +transformers/models/ernie4_5/__init__.py,sha256=5tqpitaOWvT1CdXTgMtMLCKIkUG683y3jdcTZ8yuwfM,997 +transformers/models/ernie4_5/__pycache__/__init__.cpython-310.pyc,, +transformers/models/ernie4_5/__pycache__/configuration_ernie4_5.cpython-310.pyc,, +transformers/models/ernie4_5/__pycache__/modeling_ernie4_5.cpython-310.pyc,, +transformers/models/ernie4_5/__pycache__/modular_ernie4_5.cpython-310.pyc,, +transformers/models/ernie4_5/configuration_ernie4_5.py,sha256=17rFJv-vI9AKo5VMmn4Vbo0Kg7poRurhmUNbcV4q8uo,7820 +transformers/models/ernie4_5/modeling_ernie4_5.py,sha256=3dRrxpKVhAXUp6F5oUVW7PXQ_KjyBniJbmhKkCf9CzM,21654 +transformers/models/ernie4_5/modular_ernie4_5.py,sha256=-DWvU2AvgqFoIkCidrgMKyQk2QSlFV-puDeVR88KCsk,5569 +transformers/models/ernie4_5_moe/__init__.py,sha256=MJaAQxyB3YypXN79FGJpkSvnX6KWt86iunOFXjiA7a4,1005 +transformers/models/ernie4_5_moe/__pycache__/__init__.cpython-310.pyc,, +transformers/models/ernie4_5_moe/__pycache__/configuration_ernie4_5_moe.cpython-310.pyc,, +transformers/models/ernie4_5_moe/__pycache__/modeling_ernie4_5_moe.cpython-310.pyc,, +transformers/models/ernie4_5_moe/__pycache__/modular_ernie4_5_moe.cpython-310.pyc,, +transformers/models/ernie4_5_moe/configuration_ernie4_5_moe.py,sha256=_rB52K1Iil5UhgjGT4vIhUtwwmkgjQ6xmnJg3qRs-20,10413 +transformers/models/ernie4_5_moe/modeling_ernie4_5_moe.py,sha256=DjIKkip62wbDKuFehMg2n1cHL3r0bdI5dh7MyqpLaYE,32940 +transformers/models/ernie4_5_moe/modular_ernie4_5_moe.py,sha256=V_da4Jg1h9_SDQBX_rHz6Fdy_2EHl7Lu3AQwUXbotdg,13072 +transformers/models/ernie4_5_vl_moe/__init__.py,sha256=b096LAMrXDv0c4xZqiMBN8Uqo9UZEqqc03Hy0QC-w6M,1241 +transformers/models/ernie4_5_vl_moe/__pycache__/__init__.cpython-310.pyc,, +transformers/models/ernie4_5_vl_moe/__pycache__/configuration_ernie4_5_vl_moe.cpython-310.pyc,, +transformers/models/ernie4_5_vl_moe/__pycache__/image_processing_ernie4_5_vl_moe.cpython-310.pyc,, +transformers/models/ernie4_5_vl_moe/__pycache__/image_processing_ernie4_5_vl_moe_fast.cpython-310.pyc,, +transformers/models/ernie4_5_vl_moe/__pycache__/modeling_ernie4_5_vl_moe.cpython-310.pyc,, +transformers/models/ernie4_5_vl_moe/__pycache__/modular_ernie4_5_vl_moe.cpython-310.pyc,, +transformers/models/ernie4_5_vl_moe/__pycache__/processing_ernie4_5_vl_moe.cpython-310.pyc,, +transformers/models/ernie4_5_vl_moe/__pycache__/video_processing_ernie4_5_vl_moe.cpython-310.pyc,, +transformers/models/ernie4_5_vl_moe/configuration_ernie4_5_vl_moe.py,sha256=tiq1LiAUJ-W9mUd4RalL11dIwbnZBDzKokJuyz0HUDA,17977 +transformers/models/ernie4_5_vl_moe/image_processing_ernie4_5_vl_moe.py,sha256=_qziObJTAyclhp_H8oIx9pPkqYvDVksCyG98DfvXWRQ,23710 +transformers/models/ernie4_5_vl_moe/image_processing_ernie4_5_vl_moe_fast.py,sha256=4dTxvuV1sT5h2CjuO4VpiYbl-KFUDnTCae3p8xi9M-g,10562 +transformers/models/ernie4_5_vl_moe/modeling_ernie4_5_vl_moe.py,sha256=NB4eK7Sr2WGHtv4yfNCIioGNvTlvapV6eNZWIcMJoHM,90838 +transformers/models/ernie4_5_vl_moe/modular_ernie4_5_vl_moe.py,sha256=LqGIcz61W-DTggyrj_HP6mhK-jkyVLYQRjivR14sFRo,85516 +transformers/models/ernie4_5_vl_moe/processing_ernie4_5_vl_moe.py,sha256=q6HooGYPyGaYqM_KAlbIQ7ZOfypWFEhvznGR7U35eqo,12783 +transformers/models/ernie4_5_vl_moe/video_processing_ernie4_5_vl_moe.py,sha256=H7a3L1Ubd5i4gpjvI0wOhgeOoq1SNKLGvbzbt0rb89U,25857 +transformers/models/esm/__init__.py,sha256=TT8AHFpMRg_GNzhHdNTdh120qHr5TIal5Aouok1vTCM,1059 +transformers/models/esm/__pycache__/__init__.cpython-310.pyc,, +transformers/models/esm/__pycache__/configuration_esm.cpython-310.pyc,, +transformers/models/esm/__pycache__/modeling_esm.cpython-310.pyc,, +transformers/models/esm/__pycache__/modeling_esmfold.cpython-310.pyc,, +transformers/models/esm/__pycache__/tokenization_esm.cpython-310.pyc,, +transformers/models/esm/configuration_esm.py,sha256=73FsoGv67OvMVbVTOqNWSV3aVA0WQ71lpYOVRjXcfec,13671 +transformers/models/esm/modeling_esm.py,sha256=Lc_dSe-wNNPH07G9XHcPUuvz3yAIKMYn_tp_JHLwN8M,39506 +transformers/models/esm/modeling_esmfold.py,sha256=fZHueu7QpWYLTVjUFASamw8aurTK6S4r7brHAzBbH6k,85457 +transformers/models/esm/openfold_utils/__init__.py,sha256=Xy2uqvFsLC8Ax-OOce5PgoBDiZgEJgJPqs__p5SBWUY,446 +transformers/models/esm/openfold_utils/__pycache__/__init__.cpython-310.pyc,, +transformers/models/esm/openfold_utils/__pycache__/chunk_utils.cpython-310.pyc,, +transformers/models/esm/openfold_utils/__pycache__/data_transforms.cpython-310.pyc,, +transformers/models/esm/openfold_utils/__pycache__/feats.cpython-310.pyc,, +transformers/models/esm/openfold_utils/__pycache__/loss.cpython-310.pyc,, +transformers/models/esm/openfold_utils/__pycache__/protein.cpython-310.pyc,, +transformers/models/esm/openfold_utils/__pycache__/residue_constants.cpython-310.pyc,, +transformers/models/esm/openfold_utils/__pycache__/rigid_utils.cpython-310.pyc,, +transformers/models/esm/openfold_utils/__pycache__/tensor_utils.cpython-310.pyc,, +transformers/models/esm/openfold_utils/chunk_utils.py,sha256=LoQvShWGqJyLyyHp9RB3P7ct8a87NMDKm_0FLcrCfDU,14357 +transformers/models/esm/openfold_utils/data_transforms.py,sha256=Q5J_BpJ_8Fa5fZ8nP6kPB5ops-Y4MydSQkwZ-_yMDBA,3688 +transformers/models/esm/openfold_utils/feats.py,sha256=QCYupsVINo5jJuwYk38TejNYkPlGm6Kfc1YpNUxpI8s,8355 +transformers/models/esm/openfold_utils/loss.py,sha256=ItYvWtSw-3tCUNtQjag7_kzfsKjPm8Oiy02lt1mwjqE,3661 +transformers/models/esm/openfold_utils/protein.py,sha256=MA6iShflwkUpZRwEefmT45Ll5KPU8lJ2IuJPyH2N_mI,11482 +transformers/models/esm/openfold_utils/residue_constants.py,sha256=-y44cw8jjQJakRSjn4MAMCeGhFSHoPzUCiMv9MfdGes,37875 +transformers/models/esm/openfold_utils/rigid_utils.py,sha256=gKiZUD7ngpTm7JqRJynvm-7dfrt3VLV0E0alUkFp-34,41006 +transformers/models/esm/openfold_utils/tensor_utils.py,sha256=_LAucmEB_4mVJY1oAIL1ls_5uJNpbSYv9J0PNDA6NQ8,4716 +transformers/models/esm/tokenization_esm.py,sha256=a1NTnhESsOiS3_-KdFcZgjHv93RkLi-2uANler5lIN0,5331 +transformers/models/eurobert/__init__.py,sha256=2uE76efv-JAEUyAiAkuuPLYOI20x3Vm-2Voi6c8iHc0,1060 +transformers/models/eurobert/__pycache__/__init__.cpython-310.pyc,, +transformers/models/eurobert/__pycache__/configuration_eurobert.cpython-310.pyc,, +transformers/models/eurobert/__pycache__/modeling_eurobert.cpython-310.pyc,, +transformers/models/eurobert/__pycache__/modular_eurobert.cpython-310.pyc,, +transformers/models/eurobert/configuration_eurobert.py,sha256=yUYiaZPL6V-xJt3NipOydHUq3VCpS-Qza4iny2tHclk,9056 +transformers/models/eurobert/modeling_eurobert.py,sha256=oqHeY258P80c6cNc6lD9heZ0bhfudoQNcaSNcMEjeAQ,26297 +transformers/models/eurobert/modular_eurobert.py,sha256=2zpy5ybJ0l7Dtff0R9vAjZoFC0Y9J9scVubc1ytaxZw,18976 +transformers/models/evolla/__init__.py,sha256=pOj8KGoc9jqtS_PYTeNCxZUtQrlFR_txE-kdZpiAkCw,1030 +transformers/models/evolla/__pycache__/__init__.cpython-310.pyc,, +transformers/models/evolla/__pycache__/configuration_evolla.cpython-310.pyc,, +transformers/models/evolla/__pycache__/modeling_evolla.cpython-310.pyc,, +transformers/models/evolla/__pycache__/modular_evolla.cpython-310.pyc,, +transformers/models/evolla/__pycache__/processing_evolla.cpython-310.pyc,, +transformers/models/evolla/configuration_evolla.py,sha256=pUxQrOKvnGcvDNWhWQm0TBj4H1ugWvw6wrCmybt3aFA,14484 +transformers/models/evolla/modeling_evolla.py,sha256=iKH_XXp_hxptBsNzQ19DGxjFbowv_94UxClEY2f1poU,63283 +transformers/models/evolla/modular_evolla.py,sha256=7AxLW0ZVctWVo5YlW-4AMTkNLXHt6Cf-FXHmWQQROMY,37702 +transformers/models/evolla/processing_evolla.py,sha256=nj9l_xNCRBz8-wEaraNDLR5X5gZq2-snwm_iq4lowRw,8231 +transformers/models/exaone4/__init__.py,sha256=gUDbb0olRjqxaPnB3APYKYKRlDPG2phGkfrmf7mIVD4,1018 +transformers/models/exaone4/__pycache__/__init__.cpython-310.pyc,, +transformers/models/exaone4/__pycache__/configuration_exaone4.cpython-310.pyc,, +transformers/models/exaone4/__pycache__/modeling_exaone4.cpython-310.pyc,, +transformers/models/exaone4/__pycache__/modular_exaone4.cpython-310.pyc,, +transformers/models/exaone4/configuration_exaone4.py,sha256=oPUeEn9hUhKU-klTnmRu39DqB_E9J16ogbVqGleU3LM,10273 +transformers/models/exaone4/modeling_exaone4.py,sha256=aZ26YhAJWDxvzoN8YuqKO5r6aCigiVSngefO-FWQRx8,24748 +transformers/models/exaone4/modular_exaone4.py,sha256=24LOSkefOw_jTJK_jVv_aYwZx7zLxeS3fHlsl7hmy-Y,21327 +transformers/models/exaone_moe/__init__.py,sha256=HXJMLnAy-yxDJWMl_xQ4vgzy49kgs9xR-oWUz2MF5Xw,1024 +transformers/models/exaone_moe/__pycache__/__init__.cpython-310.pyc,, +transformers/models/exaone_moe/__pycache__/configuration_exaone_moe.cpython-310.pyc,, +transformers/models/exaone_moe/__pycache__/modeling_exaone_moe.cpython-310.pyc,, +transformers/models/exaone_moe/__pycache__/modular_exaone_moe.cpython-310.pyc,, +transformers/models/exaone_moe/configuration_exaone_moe.py,sha256=2UjLNYn0peYShuQHmb5zNSnrwqz2klHqINf2iXyn5pA,12386 +transformers/models/exaone_moe/modeling_exaone_moe.py,sha256=BWGIPJ75CieUCmNyKKhbRZG_QG3KePQR5SuD14MItuU,30398 +transformers/models/exaone_moe/modular_exaone_moe.py,sha256=FBK7sAC4bkXCBvfkLOpJ4Fvp-vVa893p5fnjfBZlg3k,16982 +transformers/models/falcon/__init__.py,sha256=qmBlF_xusyrueKMfriC2ldVrHzeLIT7ruSdduMODuE4,993 +transformers/models/falcon/__pycache__/__init__.cpython-310.pyc,, +transformers/models/falcon/__pycache__/configuration_falcon.cpython-310.pyc,, +transformers/models/falcon/__pycache__/modeling_falcon.cpython-310.pyc,, +transformers/models/falcon/configuration_falcon.py,sha256=9Lp0FuPWcwmvUx7YYk-sIlVlyb-uapwdrHHZ3M6Wiw8,8808 +transformers/models/falcon/modeling_falcon.py,sha256=9L_GUlPAYMAOUmc_F5FRuQ_rCl3896uQr240Aof8bqY,56344 +transformers/models/falcon_h1/__init__.py,sha256=cpix3f3f_xMDLf2OLuyYZULnb7enZl3UZapPQuf0YZc,1012 +transformers/models/falcon_h1/__pycache__/__init__.cpython-310.pyc,, +transformers/models/falcon_h1/__pycache__/configuration_falcon_h1.cpython-310.pyc,, +transformers/models/falcon_h1/__pycache__/modeling_falcon_h1.cpython-310.pyc,, +transformers/models/falcon_h1/__pycache__/modular_falcon_h1.cpython-310.pyc,, +transformers/models/falcon_h1/configuration_falcon_h1.py,sha256=qUZ16eN7DgIiqoVyrpQNSiyqRjueAQnSX2SB12FwGgQ,15045 +transformers/models/falcon_h1/modeling_falcon_h1.py,sha256=o259SUrwhKyZLjfnFWxPUzhwpKX3adH1KbiSP6zFyqQ,69145 +transformers/models/falcon_h1/modular_falcon_h1.py,sha256=DnaVIH5WjKKbYrrN1vAyp5-xcaZf4ht-j7ubx_ymzdk,54633 +transformers/models/falcon_mamba/__init__.py,sha256=Czo-T_Nt73nvRbK-yJEZAYsU3Bxu4i1fOxFuPosiFPw,1005 +transformers/models/falcon_mamba/__pycache__/__init__.cpython-310.pyc,, +transformers/models/falcon_mamba/__pycache__/configuration_falcon_mamba.cpython-310.pyc,, +transformers/models/falcon_mamba/__pycache__/modeling_falcon_mamba.cpython-310.pyc,, +transformers/models/falcon_mamba/__pycache__/modular_falcon_mamba.cpython-310.pyc,, +transformers/models/falcon_mamba/configuration_falcon_mamba.py,sha256=hOPEaZHKxJC4GgBoIQCMU4NOcJQ0yQcEa1e8j-Wx6zM,9565 +transformers/models/falcon_mamba/modeling_falcon_mamba.py,sha256=7RerkuYQby_L1jmuGxCrhISn8X2Cumts9C6oumKFLis,43843 +transformers/models/falcon_mamba/modular_falcon_mamba.py,sha256=Ujd0NSy8ZMUhPfYaIDSegSmOQr3YKLCQa6_Hv7sPI3c,28173 +transformers/models/fast_vlm/__init__.py,sha256=5RFlXojuEHJ2nPYyxGIADcwSQCcVg1irLZPsgZvsgcQ,997 +transformers/models/fast_vlm/__pycache__/__init__.cpython-310.pyc,, +transformers/models/fast_vlm/__pycache__/configuration_fast_vlm.cpython-310.pyc,, +transformers/models/fast_vlm/__pycache__/modeling_fast_vlm.cpython-310.pyc,, +transformers/models/fast_vlm/__pycache__/modular_fast_vlm.cpython-310.pyc,, +transformers/models/fast_vlm/configuration_fast_vlm.py,sha256=rhqojsMOhJiKXg_VIb0FHflyDVZ9H2av3dFXfMdfMJE,6969 +transformers/models/fast_vlm/modeling_fast_vlm.py,sha256=ldCmIQ16OQCymT6XXDXWzJHANndHKQp6s99rKz0vieo,19440 +transformers/models/fast_vlm/modular_fast_vlm.py,sha256=kzwt_Hjw1IyFTM4qlBIcDlUcb1jFJXvf442UOIw_orY,16648 +transformers/models/fastspeech2_conformer/__init__.py,sha256=pILmX51CcqSiFGtl_dsX1yW2S_QugA3UHAT8f4psOtA,1077 +transformers/models/fastspeech2_conformer/__pycache__/__init__.cpython-310.pyc,, +transformers/models/fastspeech2_conformer/__pycache__/configuration_fastspeech2_conformer.cpython-310.pyc,, +transformers/models/fastspeech2_conformer/__pycache__/modeling_fastspeech2_conformer.cpython-310.pyc,, +transformers/models/fastspeech2_conformer/__pycache__/tokenization_fastspeech2_conformer.cpython-310.pyc,, +transformers/models/fastspeech2_conformer/configuration_fastspeech2_conformer.py,sha256=nqHCJWOkSFfzvlvGJUOLfX7uuq8QtPIhwc4iqr4ITAY,24797 +transformers/models/fastspeech2_conformer/modeling_fastspeech2_conformer.py,sha256=YMJtN8P_YS3QRH65E8JuKYqouR3lr8ptqnz696zpm4g,70272 +transformers/models/fastspeech2_conformer/tokenization_fastspeech2_conformer.py,sha256=F5D0ttj52fzIrhefFP-w7v1GQANukmv-sYW1b117hZQ,6256 +transformers/models/flaubert/__init__.py,sha256=qjdNghRds8za303ngqPdZ5rqK6zT84rcumEAjitmWi4,1038 +transformers/models/flaubert/__pycache__/__init__.cpython-310.pyc,, +transformers/models/flaubert/__pycache__/configuration_flaubert.cpython-310.pyc,, +transformers/models/flaubert/__pycache__/modeling_flaubert.cpython-310.pyc,, +transformers/models/flaubert/__pycache__/tokenization_flaubert.cpython-310.pyc,, +transformers/models/flaubert/configuration_flaubert.py,sha256=2Jln1Bqen5ezXszsBuQOTfd1mO2ZvX7NmvpPDbUvg1w,10797 +transformers/models/flaubert/modeling_flaubert.py,sha256=UxboBRkZxAq_wKx3EUPpizeBlsBfWjZH_tP5CvU1ZNc,77718 +transformers/models/flaubert/tokenization_flaubert.py,sha256=CoczyQLIL-XC4V0ug7tr3rL132vKugO2JFaeU2dq9YA,20919 +transformers/models/flava/__init__.py,sha256=UZ-PnfpalIOh2pPXWj_WSjsxjLgMBh2kKVyyLsNTUOk,1160 +transformers/models/flava/__pycache__/__init__.cpython-310.pyc,, +transformers/models/flava/__pycache__/configuration_flava.cpython-310.pyc,, +transformers/models/flava/__pycache__/image_processing_flava.cpython-310.pyc,, +transformers/models/flava/__pycache__/image_processing_flava_fast.cpython-310.pyc,, +transformers/models/flava/__pycache__/modeling_flava.cpython-310.pyc,, +transformers/models/flava/__pycache__/processing_flava.cpython-310.pyc,, +transformers/models/flava/configuration_flava.py,sha256=rVHuEug7oH2nAuRAIhu7aq8hl55aNpUa2CZuWPGNKxQ,32919 +transformers/models/flava/image_processing_flava.py,sha256=DIj0KvgVEWaT38JUmBSf-2yIWIJCUOKkNzDXqKrIsog,42407 +transformers/models/flava/image_processing_flava_fast.py,sha256=W_oL1VbU7O3K3OcONQUo18sl5wRUt_SWIHceoFENXp8,16408 +transformers/models/flava/modeling_flava.py,sha256=hlLjjLM0ES8KN7y9wr1nfH22JBDr1yDup2GurAbAX80,89356 +transformers/models/flava/processing_flava.py,sha256=gZiybXA2r8vs1P9AxGalkHDlcM6scMUhWNUyeyUe0JU,974 +transformers/models/flex_olmo/__init__.py,sha256=6_Fhd7qPsgNuP-c5XXBFy6YvzC_qExXPzfR48w19o3c,1000 +transformers/models/flex_olmo/__pycache__/__init__.cpython-310.pyc,, +transformers/models/flex_olmo/__pycache__/configuration_flex_olmo.cpython-310.pyc,, +transformers/models/flex_olmo/__pycache__/modeling_flex_olmo.cpython-310.pyc,, +transformers/models/flex_olmo/__pycache__/modular_flex_olmo.cpython-310.pyc,, +transformers/models/flex_olmo/configuration_flex_olmo.py,sha256=rMtDt0XIWBNInsV8ZSJojJFloJaeqN0fAPVsJyVE5kg,10150 +transformers/models/flex_olmo/modeling_flex_olmo.py,sha256=P01Sy3B5BYmScxPYDlSG8kPC0Vk2kuaXCEI6x1DSmyc,31234 +transformers/models/flex_olmo/modular_flex_olmo.py,sha256=Yzl5xJrEf1OPda3WdHrDCH2mhD_IFPiiD-HibjI8sO8,16000 +transformers/models/florence2/__init__.py,sha256=H4rJT4tWJithwWolb041i7SM693Y_-oO8hhdePbjYpY,1039 +transformers/models/florence2/__pycache__/__init__.cpython-310.pyc,, +transformers/models/florence2/__pycache__/configuration_florence2.cpython-310.pyc,, +transformers/models/florence2/__pycache__/modeling_florence2.cpython-310.pyc,, +transformers/models/florence2/__pycache__/modular_florence2.cpython-310.pyc,, +transformers/models/florence2/__pycache__/processing_florence2.cpython-310.pyc,, +transformers/models/florence2/configuration_florence2.py,sha256=do5yp0fGmfgHcQMbAUypctgXb4hobImpaey_rGLK13k,9830 +transformers/models/florence2/modeling_florence2.py,sha256=l5Iy1k9neGI7W7QRLQ7MsdfbXihU2oIcqluUUYbhh5M,43211 +transformers/models/florence2/modular_florence2.py,sha256=3yqlKO6K2P6TPBSgMUzqBoiS8pMAgrL1REUkzYkSckk,76814 +transformers/models/florence2/processing_florence2.py,sha256=aITPB3f8K1g35BvbRDw-7b_jElRaGr-d6uTQdKsr8bc,34330 +transformers/models/fnet/__init__.py,sha256=mgas9n6aWayAl9GsoRBmd70n-8gTEB0vq6hXceuu4QE,1057 +transformers/models/fnet/__pycache__/__init__.cpython-310.pyc,, +transformers/models/fnet/__pycache__/configuration_fnet.cpython-310.pyc,, +transformers/models/fnet/__pycache__/modeling_fnet.cpython-310.pyc,, +transformers/models/fnet/__pycache__/tokenization_fnet.cpython-310.pyc,, +transformers/models/fnet/configuration_fnet.py,sha256=asC94EQd4Jbrgxhf_JMul2dXdVnDarU2n1M5qoSEBSE,5645 +transformers/models/fnet/modeling_fnet.py,sha256=qkdOid_lfFERoCUXdQGlOaP__bErkkehP_vtsX0Ub34,42608 +transformers/models/fnet/tokenization_fnet.py,sha256=udORINJoinlRY1mE-K5CKF2RUZOFHcwW5xN2xXfWO-g,3226 +transformers/models/focalnet/__init__.py,sha256=kFk7pYv4troBIWdCYosHMKh8PAnpXqjlxaRRQ5adkG0,997 +transformers/models/focalnet/__pycache__/__init__.cpython-310.pyc,, +transformers/models/focalnet/__pycache__/configuration_focalnet.cpython-310.pyc,, +transformers/models/focalnet/__pycache__/modeling_focalnet.cpython-310.pyc,, +transformers/models/focalnet/configuration_focalnet.py,sha256=ocfvVXZyIk3sjdqviB6ZuOjbFwb2D-7LniQms7iR_aQ,7897 +transformers/models/focalnet/modeling_focalnet.py,sha256=9o2xvv-wTk9HWWJmlp2RM_0JL_v1xvRU_qTVDYenLBA,36659 +transformers/models/fsmt/__init__.py,sha256=u_Xx7d3qDicqwR_W0js1h2wPiLKWM1RlMu7fsBdIHy4,1026 +transformers/models/fsmt/__pycache__/__init__.cpython-310.pyc,, +transformers/models/fsmt/__pycache__/configuration_fsmt.cpython-310.pyc,, +transformers/models/fsmt/__pycache__/modeling_fsmt.cpython-310.pyc,, +transformers/models/fsmt/__pycache__/tokenization_fsmt.cpython-310.pyc,, +transformers/models/fsmt/configuration_fsmt.py,sha256=zMO8a6kCF9J1IUiEAASdDT12bbB92O8H4Fyzm1o58sE,10140 +transformers/models/fsmt/modeling_fsmt.py,sha256=KW_ic21kxrNZEliI08iP7PpbM089kmURzgIu_nOKiMo,46933 +transformers/models/fsmt/tokenization_fsmt.py,sha256=SUXZffNt4x4Rc3xgB3XP2pled00mgCRpkNxy9pMrr1U,17893 +transformers/models/funnel/__init__.py,sha256=Splt8ur4jydU5mQDedRgc9OIezrmQdoOXtEMb6AURDU,1100 +transformers/models/funnel/__pycache__/__init__.cpython-310.pyc,, +transformers/models/funnel/__pycache__/configuration_funnel.cpython-310.pyc,, +transformers/models/funnel/__pycache__/modeling_funnel.cpython-310.pyc,, +transformers/models/funnel/__pycache__/tokenization_funnel.cpython-310.pyc,, +transformers/models/funnel/configuration_funnel.py,sha256=0UEvUgAFlG3cK5ZeflSrIOwSP7e0jKWmICmnCKBJxJI,7969 +transformers/models/funnel/modeling_funnel.py,sha256=BwSBGjPfgwFTQII1Qupo1RjRjKgp_R8c9GS2xE5vEkg,57857 +transformers/models/funnel/tokenization_funnel.py,sha256=G2HlIGS88ivH_5DF1F7-L9Ww72RdzSYDO6XiqzZTuTI,6792 +transformers/models/fuyu/__init__.py,sha256=bZi77XDrzLji-rn9aS4eLY1Bh-hSB9Ibc6IxUkARBGk,1111 +transformers/models/fuyu/__pycache__/__init__.cpython-310.pyc,, +transformers/models/fuyu/__pycache__/configuration_fuyu.cpython-310.pyc,, +transformers/models/fuyu/__pycache__/image_processing_fuyu.cpython-310.pyc,, +transformers/models/fuyu/__pycache__/image_processing_fuyu_fast.cpython-310.pyc,, +transformers/models/fuyu/__pycache__/modeling_fuyu.cpython-310.pyc,, +transformers/models/fuyu/__pycache__/processing_fuyu.cpython-310.pyc,, +transformers/models/fuyu/configuration_fuyu.py,sha256=GD57COQ50-wXe6UYOtwnmed2VVX6bWT5J8J8S5vYh7A,8651 +transformers/models/fuyu/image_processing_fuyu.py,sha256=bXdoGjLig3EmA1Tv3q14iE8d74-Yv-sotEpHo0ZTfxA,33958 +transformers/models/fuyu/image_processing_fuyu_fast.py,sha256=lHtcgsbjmtrUiqhtxVs-Eyfm2x2M9RrPCwqJlNEVyMc,17173 +transformers/models/fuyu/modeling_fuyu.py,sha256=Cb4PfRxtBTVpoz4QmxodmF1_6GXRetBSNGqkeIFANsk,17619 +transformers/models/fuyu/processing_fuyu.py,sha256=C9VGoeAZCJSoliwU6SeTveaGIuKVKNBMn6zz4_Qbx50,35522 +transformers/models/gemma/__init__.py,sha256=LH4Ol4ZYhkhYMywv0wWsYggrcbX1UOsAMD-psGm8P-c,1072 +transformers/models/gemma/__pycache__/__init__.cpython-310.pyc,, +transformers/models/gemma/__pycache__/configuration_gemma.cpython-310.pyc,, +transformers/models/gemma/__pycache__/modeling_gemma.cpython-310.pyc,, +transformers/models/gemma/__pycache__/modular_gemma.cpython-310.pyc,, +transformers/models/gemma/__pycache__/tokenization_gemma.cpython-310.pyc,, +transformers/models/gemma/configuration_gemma.py,sha256=wQXNyYNfANO_C0oZV01zNf40p6NMYmM53uyfAlJH2jI,8843 +transformers/models/gemma/modeling_gemma.py,sha256=vxz7wcZfzfyTQQ-hmQqq407CRPBTE6FtH_mQncbBhA4,22503 +transformers/models/gemma/modular_gemma.py,sha256=asow0VPgCVmW4cugkhSWBWc0HiMK4dNXuv2mlgCYkoU,14298 +transformers/models/gemma/tokenization_gemma.py,sha256=_ySB4GmDAVGIV13GK9L6Dm8z7S0BFl2UDv53uA7o1Bk,3868 +transformers/models/gemma2/__init__.py,sha256=H0jWJX-AcGRTjdzkGJagKnjB6GnpqVUG4ODFhMF9OWM,993 +transformers/models/gemma2/__pycache__/__init__.cpython-310.pyc,, +transformers/models/gemma2/__pycache__/configuration_gemma2.cpython-310.pyc,, +transformers/models/gemma2/__pycache__/modeling_gemma2.cpython-310.pyc,, +transformers/models/gemma2/__pycache__/modular_gemma2.cpython-310.pyc,, +transformers/models/gemma2/configuration_gemma2.py,sha256=RIt2n-quaZyrI5uTpdzkaEB6Av0WKhsuVjc0muRhUwM,10528 +transformers/models/gemma2/modeling_gemma2.py,sha256=-rn8FGu1PAoDBaFSigvaBmHzQ7mZYqOfZXqFAVV5x5s,24482 +transformers/models/gemma2/modular_gemma2.py,sha256=amG5MmBSlwuBEdjoS6irPprip2I5pRMiRrrqS2RUVbM,25080 +transformers/models/gemma3/__init__.py,sha256=yDt-ADg8e57SlRlpfsC7KzQCeYYgUrTz9ZO5VC5v_W4,1121 +transformers/models/gemma3/__pycache__/__init__.cpython-310.pyc,, +transformers/models/gemma3/__pycache__/configuration_gemma3.cpython-310.pyc,, +transformers/models/gemma3/__pycache__/image_processing_gemma3.cpython-310.pyc,, +transformers/models/gemma3/__pycache__/image_processing_gemma3_fast.cpython-310.pyc,, +transformers/models/gemma3/__pycache__/modeling_gemma3.cpython-310.pyc,, +transformers/models/gemma3/__pycache__/modular_gemma3.cpython-310.pyc,, +transformers/models/gemma3/__pycache__/processing_gemma3.cpython-310.pyc,, +transformers/models/gemma3/configuration_gemma3.py,sha256=Ah4LEOUVXxbJ-RLqlTYtTwkz44ici4gQ8o_U9b2MH2U,17113 +transformers/models/gemma3/image_processing_gemma3.py,sha256=lFj0lrwXUJ5r-rt3i6zFSUIZWB9DSAFupZHovhd83jA,20426 +transformers/models/gemma3/image_processing_gemma3_fast.py,sha256=2t2vOgrDsYz4ay9T_qmUzaZaoizsB8ba9PHaBUeRxN4,10099 +transformers/models/gemma3/modeling_gemma3.py,sha256=oRFe354MSjtTZX8h4t5d4KmUiHZ9hBgdtuBeCCrbT2k,58009 +transformers/models/gemma3/modular_gemma3.py,sha256=mVZFtYPQX31U3pRB8e1q-syxLSluuC96r05VW1yFM8k,53097 +transformers/models/gemma3/processing_gemma3.py,sha256=Yfw3xLFHIsdj2pgqbIMqWX23hIW73WGZHlUR2SGPQH8,7321 +transformers/models/gemma3n/__init__.py,sha256=ZSrv5oSiULGXY7Vszb--vaJh1l7FBe1lrZD_3LX6cj4,1079 +transformers/models/gemma3n/__pycache__/__init__.cpython-310.pyc,, +transformers/models/gemma3n/__pycache__/configuration_gemma3n.cpython-310.pyc,, +transformers/models/gemma3n/__pycache__/feature_extraction_gemma3n.cpython-310.pyc,, +transformers/models/gemma3n/__pycache__/modeling_gemma3n.cpython-310.pyc,, +transformers/models/gemma3n/__pycache__/modular_gemma3n.cpython-310.pyc,, +transformers/models/gemma3n/__pycache__/processing_gemma3n.cpython-310.pyc,, +transformers/models/gemma3n/configuration_gemma3n.py,sha256=-bRuu88JctoDBLRzOUlZJz4TZEiOGGs5jfIyWfDB4Nw,35912 +transformers/models/gemma3n/feature_extraction_gemma3n.py,sha256=N8o-Mp0OJDpV7nL3g_wKq179gWIBcVsjRZA3DCuMgEA,14875 +transformers/models/gemma3n/modeling_gemma3n.py,sha256=DJTbt3eQ_IkxkgVhLAPtBa7qIm5kRZ1w9R5-GSW_OLo,114392 +transformers/models/gemma3n/modular_gemma3n.py,sha256=nkTJPR3lBPi6VDHRh2usMrmhI2sp7KwuyH_X9X28qw4,130553 +transformers/models/gemma3n/processing_gemma3n.py,sha256=L1AHdCYqg_pTEQTxPHisRKPGtjw5Dq_l1ZpRAefkrJk,6287 +transformers/models/git/__init__.py,sha256=jY1iLd7UMOmcCfrKgzoUJawLa0DQ55wHN26L09YSwhc,1021 +transformers/models/git/__pycache__/__init__.cpython-310.pyc,, +transformers/models/git/__pycache__/configuration_git.cpython-310.pyc,, +transformers/models/git/__pycache__/modeling_git.cpython-310.pyc,, +transformers/models/git/__pycache__/processing_git.cpython-310.pyc,, +transformers/models/git/configuration_git.py,sha256=BWdBIwbfndwCkjYBZaupHcn81BOBCZzhb7yQ6wX95ac,9626 +transformers/models/git/modeling_git.py,sha256=2EuhZRV7ZvYo2YIwfqb8PLmE-i1PjZ1qhzMdFXARyoU,58400 +transformers/models/git/processing_git.py,sha256=tj0eMBNee_EHZLrbVDzfodzk8C6BKXXgB4bH0W8wA4E,905 +transformers/models/glm/__init__.py,sha256=fIafw6FAflbbeG_nEM_VPJyMJHnu_NbWHTHjECIAvIs,987 +transformers/models/glm/__pycache__/__init__.cpython-310.pyc,, +transformers/models/glm/__pycache__/configuration_glm.cpython-310.pyc,, +transformers/models/glm/__pycache__/modeling_glm.cpython-310.pyc,, +transformers/models/glm/__pycache__/modular_glm.cpython-310.pyc,, +transformers/models/glm/configuration_glm.py,sha256=uYPVqY4U07twJHWBsnrzoaec8RYLS0JmJ_NmPOPj-10,7993 +transformers/models/glm/modeling_glm.py,sha256=fnXty11yk0ou2WXkkGI0kZ7mR8Z7i_oNiu0dgdAcQeM,22578 +transformers/models/glm/modular_glm.py,sha256=PAErjm8zLbyLeSPhr4JRd0HB0MRTse4k4EDWOTuqg-Y,5526 +transformers/models/glm4/__init__.py,sha256=okqViVxR-MUlkyIdKmSwrDKA7u8pGG49OIKtW9X1hvU,989 +transformers/models/glm4/__pycache__/__init__.cpython-310.pyc,, +transformers/models/glm4/__pycache__/configuration_glm4.cpython-310.pyc,, +transformers/models/glm4/__pycache__/modeling_glm4.cpython-310.pyc,, +transformers/models/glm4/__pycache__/modular_glm4.cpython-310.pyc,, +transformers/models/glm4/configuration_glm4.py,sha256=u1SNpXryjvuMc5WP_6NDiuBPoDr-SiSt1NJIjuYVqdQ,8009 +transformers/models/glm4/modeling_glm4.py,sha256=VRxgRri9lMze1yT5kb3UIsz9aaAsXKWmEe1UGzAJO_4,23454 +transformers/models/glm4/modular_glm4.py,sha256=Es0bmuAn0U6yklH31D1BTP1kysxKrwXFDGGyi07Jm_s,5125 +transformers/models/glm46v/__init__.py,sha256=cXOkEaPOTiAltGVluSMJ_MdlzNmcRrBd84xUd-1YFHM,1164 +transformers/models/glm46v/__pycache__/__init__.cpython-310.pyc,, +transformers/models/glm46v/__pycache__/configuration_glm46v.cpython-310.pyc,, +transformers/models/glm46v/__pycache__/image_processing_glm46v.cpython-310.pyc,, +transformers/models/glm46v/__pycache__/image_processing_glm46v_fast.cpython-310.pyc,, +transformers/models/glm46v/__pycache__/modeling_glm46v.cpython-310.pyc,, +transformers/models/glm46v/__pycache__/modular_glm46v.cpython-310.pyc,, +transformers/models/glm46v/__pycache__/processing_glm46v.cpython-310.pyc,, +transformers/models/glm46v/__pycache__/video_processing_glm46v.cpython-310.pyc,, +transformers/models/glm46v/configuration_glm46v.py,sha256=H3x7P9leIl06v0SUJ7Uqp24TFihi286Gug-U-32qtME,5418 +transformers/models/glm46v/image_processing_glm46v.py,sha256=2XGHRB2vFDfiaIz1R7CX06kWGCF4nibWxaxPlEdPngo,24566 +transformers/models/glm46v/image_processing_glm46v_fast.py,sha256=mUh2irCsljN1fkkmnUKlA0-DSOC5CxnwG8iO07fS-hk,7947 +transformers/models/glm46v/modeling_glm46v.py,sha256=sZ281sq5Q0R4fSMjSdPwAK3c84NAmnyyct7PN1AdXik,42159 +transformers/models/glm46v/modular_glm46v.py,sha256=Zuf6lR3DqIIRtSOZDLW82lbNdTKQU-q9TDHJ2rimhfY,8758 +transformers/models/glm46v/processing_glm46v.py,sha256=3NxjEdDb5MwE-OA7eb5XOSp3aYdo42YRLM8FYfxif84,13219 +transformers/models/glm46v/video_processing_glm46v.py,sha256=wd-yNcTdDabOueT1JG_CLdbJRzUJR6omvLsZ32kAdEc,11728 +transformers/models/glm4_moe/__init__.py,sha256=dfmB1kPUzq5-xfXh3zFtfGdSJu7CDDbfL401u_EayjM,997 +transformers/models/glm4_moe/__pycache__/__init__.cpython-310.pyc,, +transformers/models/glm4_moe/__pycache__/configuration_glm4_moe.cpython-310.pyc,, +transformers/models/glm4_moe/__pycache__/modeling_glm4_moe.cpython-310.pyc,, +transformers/models/glm4_moe/__pycache__/modular_glm4_moe.cpython-310.pyc,, +transformers/models/glm4_moe/configuration_glm4_moe.py,sha256=BH2jLLX4hLMIdh38IukFWvOnkPB3AsAS8FVJwizsMYM,11450 +transformers/models/glm4_moe/modeling_glm4_moe.py,sha256=lnDxr3lGa39th0Wq6J2Whp8hGaJzeUaqt8UmflEMqi4,29106 +transformers/models/glm4_moe/modular_glm4_moe.py,sha256=y0bXLdATAY7MKNMnbRNu3Qusr17U_w18muz97MrbFT8,13772 +transformers/models/glm4_moe_lite/__init__.py,sha256=QhYOQontNMp2Fw5CMVOJcNDD36LzURkY1csW-Y2Bpcw,1008 +transformers/models/glm4_moe_lite/__pycache__/__init__.cpython-310.pyc,, +transformers/models/glm4_moe_lite/__pycache__/configuration_glm4_moe_lite.cpython-310.pyc,, +transformers/models/glm4_moe_lite/__pycache__/modeling_glm4_moe_lite.cpython-310.pyc,, +transformers/models/glm4_moe_lite/__pycache__/modular_glm4_moe_lite.cpython-310.pyc,, +transformers/models/glm4_moe_lite/configuration_glm4_moe_lite.py,sha256=qJqPQQMTx58P0nQN3YINmCUETCnw3iLRTlDxd1rErKw,12723 +transformers/models/glm4_moe_lite/modeling_glm4_moe_lite.py,sha256=vVjJJhhjNO8vk_TlWEK9nEX1zatgbhFS2Ml7iBUKu5Y,32954 +transformers/models/glm4_moe_lite/modular_glm4_moe_lite.py,sha256=E_X0loriL8TZnE-zunFJZuYNKO6kbbhPQ-EgwMiGjNI,13589 +transformers/models/glm4v/__init__.py,sha256=emjATAJWT2oG9zrk7Qkhq08EouMBwzoYLc95lOsvYXY,1111 +transformers/models/glm4v/__pycache__/__init__.cpython-310.pyc,, +transformers/models/glm4v/__pycache__/configuration_glm4v.cpython-310.pyc,, +transformers/models/glm4v/__pycache__/image_processing_glm4v.cpython-310.pyc,, +transformers/models/glm4v/__pycache__/image_processing_glm4v_fast.cpython-310.pyc,, +transformers/models/glm4v/__pycache__/modeling_glm4v.cpython-310.pyc,, +transformers/models/glm4v/__pycache__/modular_glm4v.cpython-310.pyc,, +transformers/models/glm4v/__pycache__/processing_glm4v.cpython-310.pyc,, +transformers/models/glm4v/__pycache__/video_processing_glm4v.cpython-310.pyc,, +transformers/models/glm4v/configuration_glm4v.py,sha256=xFG94XoOD256ZyYSBAh8Hhu70vVPh35D6YgdS5hYByc,15909 +transformers/models/glm4v/image_processing_glm4v.py,sha256=Gw6gln4V_Pso_Np8JmKFUDSjxRYImzd92mZNGa6lux0,23830 +transformers/models/glm4v/image_processing_glm4v_fast.py,sha256=8ArXSJhKBPESukKeLvPoHJU7yMkjZh6x4B6CEVrc35E,7311 +transformers/models/glm4v/modeling_glm4v.py,sha256=0lkLLfIJq29ro3_RzOSdkJfm_VhSJjnUvGRKMQ0qhGw,79125 +transformers/models/glm4v/modular_glm4v.py,sha256=NUtMsRGOhMSKeL-nCTC6Zk2CSN0a0SxZwXI_zx4b5SI,71715 +transformers/models/glm4v/processing_glm4v.py,sha256=J4H9Ot35p01TpcGlY_JQPoj2xO0GVgngl4HDOyEqNyg,13229 +transformers/models/glm4v/video_processing_glm4v.py,sha256=t5vdG3JLfSfn8k7IcRZSnAYFKazd3BoxUKNVNVIpN44,9933 +transformers/models/glm4v_moe/__init__.py,sha256=4MuhU3oMjO5wL4YHEEhn0uU4qIsXz17DJPMs_xqMyHA,999 +transformers/models/glm4v_moe/__pycache__/__init__.cpython-310.pyc,, +transformers/models/glm4v_moe/__pycache__/configuration_glm4v_moe.cpython-310.pyc,, +transformers/models/glm4v_moe/__pycache__/modeling_glm4v_moe.cpython-310.pyc,, +transformers/models/glm4v_moe/__pycache__/modular_glm4v_moe.cpython-310.pyc,, +transformers/models/glm4v_moe/configuration_glm4v_moe.py,sha256=QA-Jx5BRK3GEdWkHBFYse4Lpq3nQDPIeuq6TXfkVowM,18794 +transformers/models/glm4v_moe/modeling_glm4v_moe.py,sha256=J1mWUVSG4KC0Zy_QB4sFit9J1mRLIHJHeJg3qkNN7io,90383 +transformers/models/glm4v_moe/modular_glm4v_moe.py,sha256=qDBLwQtYEzlVEGHiaHkSR_YIuhZIT5x7yQQsTEsZne0,25470 +transformers/models/glm_image/__init__.py,sha256=Y5MpC55fr1lus7NV8vp4FSo5a6YMSdGdlM2228Xd4Jc,1137 +transformers/models/glm_image/__pycache__/__init__.cpython-310.pyc,, +transformers/models/glm_image/__pycache__/configuration_glm_image.cpython-310.pyc,, +transformers/models/glm_image/__pycache__/image_processing_glm_image.cpython-310.pyc,, +transformers/models/glm_image/__pycache__/image_processing_glm_image_fast.cpython-310.pyc,, +transformers/models/glm_image/__pycache__/modeling_glm_image.cpython-310.pyc,, +transformers/models/glm_image/__pycache__/modular_glm_image.cpython-310.pyc,, +transformers/models/glm_image/__pycache__/processing_glm_image.cpython-310.pyc,, +transformers/models/glm_image/configuration_glm_image.py,sha256=n7FlX3j33TK6Xryf3xCrIKM55lxH1zQNSteii9uw6j4,17537 +transformers/models/glm_image/image_processing_glm_image.py,sha256=2rPFtmOhu6639zBLrwytsPfLwXjQCxV3bk4Jp4oE9Mg,25285 +transformers/models/glm_image/image_processing_glm_image_fast.py,sha256=eyXiFvevFUkxYVhAkXnoyp0bbIIdt2GNJz3ZlnXUF94,12298 +transformers/models/glm_image/modeling_glm_image.py,sha256=nN0Co_QAwEW9-5RBYUZzqlZQnl2L0mYw_ZPwantOV4I,78269 +transformers/models/glm_image/modular_glm_image.py,sha256=4PR2YwVAzk9QkL8t5zrtYkfMkaHWxNTlY3UYOVua7t0,72027 +transformers/models/glm_image/processing_glm_image.py,sha256=nttdFQH3I_V58v17Z9ssbhfDmqX8rNWpjGP2dc_2gOs,12117 +transformers/models/glm_moe_dsa/__init__.py,sha256=sW2Trp4R9zjg37__07KUEMPo4dkirLgDtHthTsViU-Y,1004 +transformers/models/glm_moe_dsa/__pycache__/__init__.cpython-310.pyc,, +transformers/models/glm_moe_dsa/__pycache__/configuration_glm_moe_dsa.cpython-310.pyc,, +transformers/models/glm_moe_dsa/__pycache__/modeling_glm_moe_dsa.cpython-310.pyc,, +transformers/models/glm_moe_dsa/__pycache__/modular_glm_moe_dsa.cpython-310.pyc,, +transformers/models/glm_moe_dsa/configuration_glm_moe_dsa.py,sha256=2vhYcdGa003yr-G42YM0gEMbH0E3IBSpDWTShivOWTo,12441 +transformers/models/glm_moe_dsa/modeling_glm_moe_dsa.py,sha256=RL_In1WqnGI74EavS5KNdtFtDf5kAP2p8ccEwi4_Atw,40012 +transformers/models/glm_moe_dsa/modular_glm_moe_dsa.py,sha256=xygw_hpgI2G5KaJBkIDNmPuC8ZI6E4nN9-LU0VYJuSE,29247 +transformers/models/glm_ocr/__init__.py,sha256=oeeKm635ED_6WvzpS6UgtVQK8Czp18lLyVVzsHNU8NE,996 +transformers/models/glm_ocr/__pycache__/__init__.cpython-310.pyc,, +transformers/models/glm_ocr/__pycache__/configuration_glm_ocr.cpython-310.pyc,, +transformers/models/glm_ocr/__pycache__/modeling_glm_ocr.cpython-310.pyc,, +transformers/models/glm_ocr/__pycache__/modular_glm_ocr.cpython-310.pyc,, +transformers/models/glm_ocr/configuration_glm_ocr.py,sha256=qE8gkUT96v0zdYkewjCmYX1VJ3AuXRUI4nN9UaMYMGc,15495 +transformers/models/glm_ocr/modeling_glm_ocr.py,sha256=q8yngXUs4OjSvgapmYMNUPwuwSK85rkbyxnKNHn7j6I,75803 +transformers/models/glm_ocr/modular_glm_ocr.py,sha256=8JvqP4oa8sNXQdmXZ--yfKdmzF4hmfTWFZ-MsFPVBR0,18622 +transformers/models/glmasr/__init__.py,sha256=UpS-w64zO1l1qsMI0GggLWffkdh2EKlW08BISsMiZz4,1031 +transformers/models/glmasr/__pycache__/__init__.cpython-310.pyc,, +transformers/models/glmasr/__pycache__/configuration_glmasr.cpython-310.pyc,, +transformers/models/glmasr/__pycache__/modeling_glmasr.cpython-310.pyc,, +transformers/models/glmasr/__pycache__/modular_glmasr.cpython-310.pyc,, +transformers/models/glmasr/__pycache__/processing_glmasr.cpython-310.pyc,, +transformers/models/glmasr/configuration_glmasr.py,sha256=8GM-bOIsgnqUC05Plaz7X1UuPvvQ5vCDjpVZN76s1eA,8835 +transformers/models/glmasr/modeling_glmasr.py,sha256=weE4lgzys9hpqebu7EWSfnOevkGX3fVO_Q9IHe5xkr0,22804 +transformers/models/glmasr/modular_glmasr.py,sha256=aAqcv6AaNST402ce71_EISQs6T0wf1bLBg4vQVDWXCU,18856 +transformers/models/glmasr/processing_glmasr.py,sha256=kIwDrKqMefE543ChY9EGMKmvvEwxFYsAXwN6kHkLXdA,14446 +transformers/models/glpn/__init__.py,sha256=kZWLi39Z6IaKfiAJ5WSbQwAqYExpBxQDwl8ZVPASC4M,1119 +transformers/models/glpn/__pycache__/__init__.cpython-310.pyc,, +transformers/models/glpn/__pycache__/configuration_glpn.cpython-310.pyc,, +transformers/models/glpn/__pycache__/image_processing_glpn.cpython-310.pyc,, +transformers/models/glpn/__pycache__/image_processing_glpn_fast.cpython-310.pyc,, +transformers/models/glpn/__pycache__/modeling_glpn.cpython-310.pyc,, +transformers/models/glpn/configuration_glpn.py,sha256=Y2K-2yI5DDsYx0HjvVUsEnuZX-iP9o5klmx0f-D2-Hg,5983 +transformers/models/glpn/image_processing_glpn.py,sha256=2O2wM__kTSjoxvOW4iFwDjRuFFoJAPKfyju5CZYBWsM,13305 +transformers/models/glpn/image_processing_glpn_fast.py,sha256=X7RAD_xMhUFD7qYduukurP4zWEDR7P2-QLX5FAUQr4Y,5247 +transformers/models/glpn/modeling_glpn.py,sha256=AFBmOospzJRMfP7V_XNBjvnYcnm1wG3gB8L1Z7ZaLlg,26384 +transformers/models/got_ocr2/__init__.py,sha256=LBVZP8CBfOxaD9NLC2ZbZpLloHLIX7uDyM8m1-W2m6g,1138 +transformers/models/got_ocr2/__pycache__/__init__.cpython-310.pyc,, +transformers/models/got_ocr2/__pycache__/configuration_got_ocr2.cpython-310.pyc,, +transformers/models/got_ocr2/__pycache__/image_processing_got_ocr2.cpython-310.pyc,, +transformers/models/got_ocr2/__pycache__/image_processing_got_ocr2_fast.cpython-310.pyc,, +transformers/models/got_ocr2/__pycache__/modeling_got_ocr2.cpython-310.pyc,, +transformers/models/got_ocr2/__pycache__/modular_got_ocr2.cpython-310.pyc,, +transformers/models/got_ocr2/__pycache__/processing_got_ocr2.cpython-310.pyc,, +transformers/models/got_ocr2/configuration_got_ocr2.py,sha256=KK4g69VwJQFVXH7RM6KAkA3LhVEE0MRgqWrO6Ab8n-o,9581 +transformers/models/got_ocr2/image_processing_got_ocr2.py,sha256=eM2_HKYRDjikiEjgYr7fuRo5R3OI-HXJDlK1vYka9c4,26180 +transformers/models/got_ocr2/image_processing_got_ocr2_fast.py,sha256=DkmL05hstkivTg_-2W0lRn_aXp6674sVOh1uAh-IeA0,9453 +transformers/models/got_ocr2/modeling_got_ocr2.py,sha256=QGhBbKGfklirPj8y4HyROHKMoNNt4nWGf0Mya0lPyxg,36070 +transformers/models/got_ocr2/modular_got_ocr2.py,sha256=4Q9RtyVQDCgY0-UaFrTK1vjLmztZrUSK83LisgWA-rk,20095 +transformers/models/got_ocr2/processing_got_ocr2.py,sha256=sfqk_UZ1H83uNNU8gGhawieUz8anxa7dWiQd1y5cwNQ,10450 +transformers/models/gpt2/__init__.py,sha256=trifYw4vnBNfaiVq-8aSyPTNAGWdUE-eSOVJfR28nhE,1026 +transformers/models/gpt2/__pycache__/__init__.cpython-310.pyc,, +transformers/models/gpt2/__pycache__/configuration_gpt2.cpython-310.pyc,, +transformers/models/gpt2/__pycache__/modeling_gpt2.cpython-310.pyc,, +transformers/models/gpt2/__pycache__/tokenization_gpt2.cpython-310.pyc,, +transformers/models/gpt2/configuration_gpt2.py,sha256=IiGAR8Mz-Ezks9cIfCBFwimCMAxPwn0cekWQWZQ_BhA,9071 +transformers/models/gpt2/modeling_gpt2.py,sha256=779RvYblrKh-ZrGZE7Kb9EnmUjbP0dZOM5Hr5U_huIc,52624 +transformers/models/gpt2/tokenization_gpt2.py,sha256=qdvEf7AwS5jMmgxGQrkpJHP5ZlLInB8dePQgYTU18eU,5370 +transformers/models/gpt_bigcode/__init__.py,sha256=KQNb7PO57eZpP345wSbe_C3iL-N4VPscw1GY2mv81uE,1003 +transformers/models/gpt_bigcode/__pycache__/__init__.cpython-310.pyc,, +transformers/models/gpt_bigcode/__pycache__/configuration_gpt_bigcode.cpython-310.pyc,, +transformers/models/gpt_bigcode/__pycache__/modeling_gpt_bigcode.cpython-310.pyc,, +transformers/models/gpt_bigcode/configuration_gpt_bigcode.py,sha256=R39nA_YIPBqmR95jAmCVJIvrTfrKl1GAfqY-_QFgfBA,6553 +transformers/models/gpt_bigcode/modeling_gpt_bigcode.py,sha256=r1HOx_8SxmkkrzQ-9PsF9xrp4k9Jt6ia88gCkti_AmA,38283 +transformers/models/gpt_neo/__init__.py,sha256=OG3bA-FgdEYzI3Qs45XGMCa-4zdz5F9zQycsYBXuQ_4,995 +transformers/models/gpt_neo/__pycache__/__init__.cpython-310.pyc,, +transformers/models/gpt_neo/__pycache__/configuration_gpt_neo.cpython-310.pyc,, +transformers/models/gpt_neo/__pycache__/modeling_gpt_neo.cpython-310.pyc,, +transformers/models/gpt_neo/configuration_gpt_neo.py,sha256=6KUFt4ElA0b0aokLFZEpg_ij9DIVtGl10NVNuRwpBRk,9425 +transformers/models/gpt_neo/modeling_gpt_neo.py,sha256=cuyDeOIBBaQUd2PtIZ4j3dGnLrZ7I9cIbezTLxQ9X3E,39093 +transformers/models/gpt_neox/__init__.py,sha256=vH3qZOHNV6DsvrKyPvzXoO_D26e0N78HDOYSlxMWTYQ,1038 +transformers/models/gpt_neox/__pycache__/__init__.cpython-310.pyc,, +transformers/models/gpt_neox/__pycache__/configuration_gpt_neox.cpython-310.pyc,, +transformers/models/gpt_neox/__pycache__/modeling_gpt_neox.cpython-310.pyc,, +transformers/models/gpt_neox/__pycache__/modular_gpt_neox.cpython-310.pyc,, +transformers/models/gpt_neox/__pycache__/tokenization_gpt_neox.cpython-310.pyc,, +transformers/models/gpt_neox/configuration_gpt_neox.py,sha256=F5ED8s1f9VfLa_hUPPjqqkySXKCYMUtdW58udAEmbn0,8807 +transformers/models/gpt_neox/modeling_gpt_neox.py,sha256=DOLe7A-x1WM0APwI0_OtTDI_FgIrtC_IZePZDUILRbI,28875 +transformers/models/gpt_neox/modular_gpt_neox.py,sha256=BSqfV38rMAkT7n34QNt3PmibS8dwc3OcRsfoG-J_dLs,25894 +transformers/models/gpt_neox/tokenization_gpt_neox.py,sha256=95fZUdUeBU-NIzFvK7gK7DomOm0B9pMrduJlXYyr8e8,6004 +transformers/models/gpt_neox_japanese/__init__.py,sha256=z4kbUmZSjE-Hs9ba8ul3Yncc9ZJy7ePufbwwRlfqWqw,1065 +transformers/models/gpt_neox_japanese/__pycache__/__init__.cpython-310.pyc,, +transformers/models/gpt_neox_japanese/__pycache__/configuration_gpt_neox_japanese.cpython-310.pyc,, +transformers/models/gpt_neox_japanese/__pycache__/modeling_gpt_neox_japanese.cpython-310.pyc,, +transformers/models/gpt_neox_japanese/__pycache__/tokenization_gpt_neox_japanese.cpython-310.pyc,, +transformers/models/gpt_neox_japanese/configuration_gpt_neox_japanese.py,sha256=y6Qts9NgoiNBDyLgnvJNpAR0zXi8kS6VdHNNdD7iJ0U,6988 +transformers/models/gpt_neox_japanese/modeling_gpt_neox_japanese.py,sha256=lDxBDPDegdZA4n21BD_Wdw4wK7FIs2xzRqFUc6bFGgM,25866 +transformers/models/gpt_neox_japanese/tokenization_gpt_neox_japanese.py,sha256=0DiKz_OKPMHfUIEXHj2eOizNdvHOP5Ib5CCwj-sbRPs,16931 +transformers/models/gpt_oss/__init__.py,sha256=a3dnVKgP6RwbuxBJW3kodYKj8oVF5Y6pLJixMthP1yA,995 +transformers/models/gpt_oss/__pycache__/__init__.cpython-310.pyc,, +transformers/models/gpt_oss/__pycache__/configuration_gpt_oss.cpython-310.pyc,, +transformers/models/gpt_oss/__pycache__/modeling_gpt_oss.cpython-310.pyc,, +transformers/models/gpt_oss/__pycache__/modular_gpt_oss.cpython-310.pyc,, +transformers/models/gpt_oss/configuration_gpt_oss.py,sha256=619xtpoSRYzSvd6nSngK3raJlbRlflgob5x7G9Fd1sc,4697 +transformers/models/gpt_oss/modeling_gpt_oss.py,sha256=M3A1SF0J05wLABt-K14SsuY0CQ8SSVCb8is2e_5hJes,31464 +transformers/models/gpt_oss/modular_gpt_oss.py,sha256=CGOEZ4BchN3zjd-0opXfDDGw5CfRr9Yvs-anEyqInxI,17946 +transformers/models/gpt_sw3/__init__.py,sha256=-g6WlJ6EhhrJKCCsPf78cgvGD7oWvfeW9GBGBpW6wcM,958 +transformers/models/gpt_sw3/__pycache__/__init__.cpython-310.pyc,, +transformers/models/gpt_sw3/__pycache__/tokenization_gpt_sw3.cpython-310.pyc,, +transformers/models/gpt_sw3/tokenization_gpt_sw3.py,sha256=Ia96IzTjuLUWbK2oHgvVfhgwMmI83Vf3tHupH-x3umo,10021 +transformers/models/gptj/__init__.py,sha256=8X2gitvP4-NmFJp4CE22JAuc0DrUHg9-lAty6XqyBkE,989 +transformers/models/gptj/__pycache__/__init__.cpython-310.pyc,, +transformers/models/gptj/__pycache__/configuration_gptj.cpython-310.pyc,, +transformers/models/gptj/__pycache__/modeling_gptj.cpython-310.pyc,, +transformers/models/gptj/configuration_gptj.py,sha256=T8Sly2fDdCgxd3EWeZEepBFDA1ihw1d59iZYoLyqomI,5492 +transformers/models/gptj/modeling_gptj.py,sha256=3uxamVCYcohIvcJOW9exLYliALkztxeGQrP027eowys,37651 +transformers/models/granite/__init__.py,sha256=cDxmZNuphkDCs2U8W5C95Vhu577kdZHKHUWWaQ3vk5U,1015 +transformers/models/granite/__pycache__/__init__.cpython-310.pyc,, +transformers/models/granite/__pycache__/configuration_granite.cpython-310.pyc,, +transformers/models/granite/__pycache__/modeling_granite.cpython-310.pyc,, +transformers/models/granite/__pycache__/modular_granite.cpython-310.pyc,, +transformers/models/granite/configuration_granite.py,sha256=UIuAA8Vq5D_aBKZ4Y1Z0XJLUgMx_Nc33ZtjdMETOdb0,9062 +transformers/models/granite/modeling_granite.py,sha256=Ifrqvu0G-vX9j2rE8YVTPPDekDEbIaI_ITE2jmRHwHY,25965 +transformers/models/granite/modular_granite.py,sha256=a5a0E_yY3f00dUfmnJG3nwBYxmgF--jENs3Pqt_-018,11482 +transformers/models/granite_speech/__init__.py,sha256=xD_zbTTnBiaB6EEG4yinaWd-yza1waa01GNKVhsGL1M,1107 +transformers/models/granite_speech/__pycache__/__init__.cpython-310.pyc,, +transformers/models/granite_speech/__pycache__/configuration_granite_speech.cpython-310.pyc,, +transformers/models/granite_speech/__pycache__/feature_extraction_granite_speech.cpython-310.pyc,, +transformers/models/granite_speech/__pycache__/modeling_granite_speech.cpython-310.pyc,, +transformers/models/granite_speech/__pycache__/processing_granite_speech.cpython-310.pyc,, +transformers/models/granite_speech/configuration_granite_speech.py,sha256=SpaGZOP9TfPDP3GPbHbDOAVh3w8yb7N2zmrd_zCjbuo,8550 +transformers/models/granite_speech/feature_extraction_granite_speech.py,sha256=Ll7tLm3n75dseBGXYm3uhgKV2Rj2javxY0XchtY8x2A,7349 +transformers/models/granite_speech/modeling_granite_speech.py,sha256=1x6T1emVPB8KyMkSuwGJqDXsetAB9yJHo-gYhzeeH-A,26742 +transformers/models/granite_speech/processing_granite_speech.py,sha256=XET-j4EGK4Fem-NmNdO_dqZFpk5m9X5R-60P2oUbV5g,4180 +transformers/models/granitemoe/__init__.py,sha256=e4KKtNT7YFkYkPBfcS0VyhpT_1vF0JkR2qdYKPqRUcE,1001 +transformers/models/granitemoe/__pycache__/__init__.cpython-310.pyc,, +transformers/models/granitemoe/__pycache__/configuration_granitemoe.cpython-310.pyc,, +transformers/models/granitemoe/__pycache__/modeling_granitemoe.cpython-310.pyc,, +transformers/models/granitemoe/__pycache__/modular_granitemoe.cpython-310.pyc,, +transformers/models/granitemoe/configuration_granitemoe.py,sha256=RnZBCrGsvi1cs8_q5Picea0_Idbn--Ywq4Tdcmbf_Pg,9162 +transformers/models/granitemoe/modeling_granitemoe.py,sha256=FhPbph7afkLPwpVn5n6JMqe-44CPovpTgwnmydYJp84,32390 +transformers/models/granitemoe/modular_granitemoe.py,sha256=9Rh4-f0NwuRqdPxl0KO7BCGl1n_EGWncChkJ9_IDjk4,13313 +transformers/models/granitemoehybrid/__init__.py,sha256=V5SQbC7YI-EoIlyHo5LoSpJ7SyuquuA5DcsuNlRoSVI,1028 +transformers/models/granitemoehybrid/__pycache__/__init__.cpython-310.pyc,, +transformers/models/granitemoehybrid/__pycache__/configuration_granitemoehybrid.cpython-310.pyc,, +transformers/models/granitemoehybrid/__pycache__/modeling_granitemoehybrid.cpython-310.pyc,, +transformers/models/granitemoehybrid/__pycache__/modular_granitemoehybrid.cpython-310.pyc,, +transformers/models/granitemoehybrid/configuration_granitemoehybrid.py,sha256=zpmWphmapVh0g4MSkxV6mh2Qmbc6xN19jNzUSz1Hl_g,13165 +transformers/models/granitemoehybrid/modeling_granitemoehybrid.py,sha256=cLVgU45QXQID39EXu9DM7ChXX3G_scjjX-qC8U8r2f8,71545 +transformers/models/granitemoehybrid/modular_granitemoehybrid.py,sha256=8hDgl-j4_pUfU6koIitcUUkD6OoUnU3x_XPw_UItB9I,14154 +transformers/models/granitemoeshared/__init__.py,sha256=vmY98tLts1c_yvkLn9X-xk6CFtXIKskzYvFGMqQAskc,1013 +transformers/models/granitemoeshared/__pycache__/__init__.cpython-310.pyc,, +transformers/models/granitemoeshared/__pycache__/configuration_granitemoeshared.cpython-310.pyc,, +transformers/models/granitemoeshared/__pycache__/modeling_granitemoeshared.cpython-310.pyc,, +transformers/models/granitemoeshared/__pycache__/modular_granitemoeshared.cpython-310.pyc,, +transformers/models/granitemoeshared/configuration_granitemoeshared.py,sha256=hn8mUTqchXpPQdnTFPhbgEn_IgsThwUXGL75tZNSvvE,9715 +transformers/models/granitemoeshared/modeling_granitemoeshared.py,sha256=b5Day2g1SHbi61vuHdBIVP0F1EZA3UeyldMkNPjhvxs,35168 +transformers/models/granitemoeshared/modular_granitemoeshared.py,sha256=mTOAGg3Nr1HFOsVlAxrI-jjo1FjiacG6aMIzrdd42iE,5707 +transformers/models/grounding_dino/__init__.py,sha256=nTxZfZioCpS8hj_L80qZQkgPviMZrTxkz14B9sQQJjk,1161 +transformers/models/grounding_dino/__pycache__/__init__.cpython-310.pyc,, +transformers/models/grounding_dino/__pycache__/configuration_grounding_dino.cpython-310.pyc,, +transformers/models/grounding_dino/__pycache__/image_processing_grounding_dino.cpython-310.pyc,, +transformers/models/grounding_dino/__pycache__/image_processing_grounding_dino_fast.cpython-310.pyc,, +transformers/models/grounding_dino/__pycache__/modeling_grounding_dino.cpython-310.pyc,, +transformers/models/grounding_dino/__pycache__/modular_grounding_dino.cpython-310.pyc,, +transformers/models/grounding_dino/__pycache__/processing_grounding_dino.cpython-310.pyc,, +transformers/models/grounding_dino/configuration_grounding_dino.py,sha256=4_Jvq2ojgwBXkWmC1j0oTtmOypd-g36Px1ZG7Go-D8E,12796 +transformers/models/grounding_dino/image_processing_grounding_dino.py,sha256=2MvSGLiG97z7omdb7D2w2HiplVwUA78QHBLfXrd2CHs,68499 +transformers/models/grounding_dino/image_processing_grounding_dino_fast.py,sha256=0Tc5Q1fnpBPlmFSbv6HKzKUvzmjB-seH2Xg_e1LqVpk,30362 +transformers/models/grounding_dino/modeling_grounding_dino.py,sha256=7uNqDzigGPoVeulS3QoDMh2-L0YSEwfNa4_QJPiPC6E,129150 +transformers/models/grounding_dino/modular_grounding_dino.py,sha256=UIu-gc19YF8Q1Yi8DAZCa6dDzLTrDLj1BiUwhI0JWe0,5575 +transformers/models/grounding_dino/processing_grounding_dino.py,sha256=-HQ14qL3SOeK_CnRWTeKJx5MdjqvourWN8eZsweBkMk,9659 +transformers/models/groupvit/__init__.py,sha256=8z8yBl-b-usbrGBx0-rNE-6pqPf4jPP_Ev4U5t8Sphc,997 +transformers/models/groupvit/__pycache__/__init__.cpython-310.pyc,, +transformers/models/groupvit/__pycache__/configuration_groupvit.cpython-310.pyc,, +transformers/models/groupvit/__pycache__/modeling_groupvit.cpython-310.pyc,, +transformers/models/groupvit/configuration_groupvit.py,sha256=kTJzZ89-l6Az-OwVQEezVCPjOERnocQI-cfdAcMyojM,17149 +transformers/models/groupvit/modeling_groupvit.py,sha256=RCHgiOmptkXzHTNh2nQzhYKu5FMZBHYLBi3hEcQRJ5k,58859 +transformers/models/helium/__init__.py,sha256=b1Senw5Mr129rzZSd1sW6-Ies2kIAUHfplpzgGeuTFE,993 +transformers/models/helium/__pycache__/__init__.cpython-310.pyc,, +transformers/models/helium/__pycache__/configuration_helium.cpython-310.pyc,, +transformers/models/helium/__pycache__/modeling_helium.cpython-310.pyc,, +transformers/models/helium/__pycache__/modular_helium.cpython-310.pyc,, +transformers/models/helium/configuration_helium.py,sha256=RZWs6kg7b-JLVUmAde7EKaqaVSai3XuNImYbk9EpYWg,7988 +transformers/models/helium/modeling_helium.py,sha256=eLCuf_4eXzFbnVWG8jgshonn2mow0Po9bYF0mWGU8eQ,21943 +transformers/models/helium/modular_helium.py,sha256=UfVwU2XOvCSRaG0BAfKekfMwp2C1qPbieXHPl70VcDY,5261 +transformers/models/herbert/__init__.py,sha256=TSI8jVDbbhzcO4Bl6xkcmLyL9VtLWTV8JuPy2_dk2sE,958 +transformers/models/herbert/__pycache__/__init__.cpython-310.pyc,, +transformers/models/herbert/__pycache__/tokenization_herbert.cpython-310.pyc,, +transformers/models/herbert/tokenization_herbert.py,sha256=d8uN5yO5NnTeA_70H-N9W9xNwrMBiRo8yrxHMrCgCWw,3917 +transformers/models/hgnet_v2/__init__.py,sha256=sBFNC0RNpS-oEnOiwtxy2SkUPAJgmI5uXXq2WjSHRd8,999 +transformers/models/hgnet_v2/__pycache__/__init__.cpython-310.pyc,, +transformers/models/hgnet_v2/__pycache__/configuration_hgnet_v2.cpython-310.pyc,, +transformers/models/hgnet_v2/__pycache__/modeling_hgnet_v2.cpython-310.pyc,, +transformers/models/hgnet_v2/__pycache__/modular_hgnet_v2.cpython-310.pyc,, +transformers/models/hgnet_v2/configuration_hgnet_v2.py,sha256=VzmmGzR9VkQtOB8_1D-uw0o_kPZ8D5GPZXfcLE-NVzY,8663 +transformers/models/hgnet_v2/modeling_hgnet_v2.py,sha256=opRD_F27Kwn2nk1aE6243LrKDo7GMCjOhvNA6LwoyJ4,18412 +transformers/models/hgnet_v2/modular_hgnet_v2.py,sha256=ZXvUpeJupmh6sesbOxjcGdX_xSqwFLaMLycyvbFWGgE,24713 +transformers/models/hiera/__init__.py,sha256=b1kwKtpZVISJZ5Pri421uvH2v3IoRQ6XXHzxFOPHN-g,991 +transformers/models/hiera/__pycache__/__init__.cpython-310.pyc,, +transformers/models/hiera/__pycache__/configuration_hiera.cpython-310.pyc,, +transformers/models/hiera/__pycache__/modeling_hiera.cpython-310.pyc,, +transformers/models/hiera/configuration_hiera.py,sha256=UuJ_NG3_4qIfvDPtRzQHrXassQKWuPAucVp_wXJaVeo,9159 +transformers/models/hiera/modeling_hiera.py,sha256=6h2x8SZGB-PL7P8o3T9H13UiJuLGqXl1gB6OPNSJXZg,59539 +transformers/models/higgs_audio_v2/__init__.py,sha256=9l-ZUYNLVBO3B2pD0KIGMtietlzt1r8TOMcPBpIUHug,1112 +transformers/models/higgs_audio_v2/__pycache__/__init__.cpython-310.pyc,, +transformers/models/higgs_audio_v2/__pycache__/configuration_higgs_audio_v2.cpython-310.pyc,, +transformers/models/higgs_audio_v2/__pycache__/generation_higgs_audio_v2.cpython-310.pyc,, +transformers/models/higgs_audio_v2/__pycache__/modeling_higgs_audio_v2.cpython-310.pyc,, +transformers/models/higgs_audio_v2/__pycache__/modular_higgs_audio_v2.cpython-310.pyc,, +transformers/models/higgs_audio_v2/__pycache__/processing_higgs_audio_v2.cpython-310.pyc,, +transformers/models/higgs_audio_v2/configuration_higgs_audio_v2.py,sha256=Tti897jtPAk2n1t0WuVaGEtp2k8LURgMWIvIMtEub90,11550 +transformers/models/higgs_audio_v2/generation_higgs_audio_v2.py,sha256=NJXE-7ldXBi22wFP7Gz9_Oqq9YqDBB895zvs5DsPo1g,22348 +transformers/models/higgs_audio_v2/modeling_higgs_audio_v2.py,sha256=GSw35HboJr-sbrLaQKqxdpRpm7d5xA2fZ6scZLBJrqI,36197 +transformers/models/higgs_audio_v2/modular_higgs_audio_v2.py,sha256=IsEioGvEG7SBHCHgRRp--h5pW2imozP1r8atyRdyoVs,31622 +transformers/models/higgs_audio_v2/processing_higgs_audio_v2.py,sha256=kC9HMmCuUO5jCeFcXy_llNVkspT2sV5kQaI2iLmqoUU,16147 +transformers/models/higgs_audio_v2_tokenizer/__init__.py,sha256=kQTOrcA2fLHDOwYqe2krRCBnDLRXKHbagiAxFHYOOk4,1042 +transformers/models/higgs_audio_v2_tokenizer/__pycache__/__init__.cpython-310.pyc,, +transformers/models/higgs_audio_v2_tokenizer/__pycache__/configuration_higgs_audio_v2_tokenizer.cpython-310.pyc,, +transformers/models/higgs_audio_v2_tokenizer/__pycache__/modeling_higgs_audio_v2_tokenizer.cpython-310.pyc,, +transformers/models/higgs_audio_v2_tokenizer/__pycache__/modular_higgs_audio_v2_tokenizer.cpython-310.pyc,, +transformers/models/higgs_audio_v2_tokenizer/configuration_higgs_audio_v2_tokenizer.py,sha256=q1oki1M_i-GEt6hox3XenHkZlJeQaUFhYB0OiCe2G8Q,8981 +transformers/models/higgs_audio_v2_tokenizer/modeling_higgs_audio_v2_tokenizer.py,sha256=WmF3aJi3RkehykUSykuygG6Bb03TZyfaUv6gxDIzRrc,28200 +transformers/models/higgs_audio_v2_tokenizer/modular_higgs_audio_v2_tokenizer.py,sha256=1v1fDyY96blUb_u4ITCVCAWYJO7Fy6t0F8f4CoZFmsQ,8305 +transformers/models/hubert/__init__.py,sha256=99_KVlRuVQxpVPnX_qPki0yEzJpggZOD527N_-aFvYM,993 +transformers/models/hubert/__pycache__/__init__.cpython-310.pyc,, +transformers/models/hubert/__pycache__/configuration_hubert.cpython-310.pyc,, +transformers/models/hubert/__pycache__/modeling_hubert.cpython-310.pyc,, +transformers/models/hubert/__pycache__/modular_hubert.cpython-310.pyc,, +transformers/models/hubert/configuration_hubert.py,sha256=l4KqllLpemnEwFzFgTz8XIHP6GvINVpBrZYdL5KVlRU,14989 +transformers/models/hubert/modeling_hubert.py,sha256=4Hf8cTGpiet37XTfTEyTRz_14w8b-VRVFsf-I2RyWVs,51235 +transformers/models/hubert/modular_hubert.py,sha256=tMstLJ6jk7UNqWHj4-7wL9cU2BMq0DwhqyOmJuppXvA,11984 +transformers/models/hunyuan_v1_dense/__init__.py,sha256=FZn7rOtjmLA5vwEeH99QcgAveRMl1LbHQOyBKhywPWY,442 +transformers/models/hunyuan_v1_dense/__pycache__/__init__.cpython-310.pyc,, +transformers/models/hunyuan_v1_dense/__pycache__/configuration_hunyuan_v1_dense.cpython-310.pyc,, +transformers/models/hunyuan_v1_dense/__pycache__/modeling_hunyuan_v1_dense.cpython-310.pyc,, +transformers/models/hunyuan_v1_dense/__pycache__/modular_hunyuan_v1_dense.cpython-310.pyc,, +transformers/models/hunyuan_v1_dense/configuration_hunyuan_v1_dense.py,sha256=0bxgHyncMBPEdX99hT6jHaSLHVQl9SWBk1AL3V5ai8Q,8027 +transformers/models/hunyuan_v1_dense/modeling_hunyuan_v1_dense.py,sha256=pv0gHP-cgvm8dvxT2qo5dSo7ITcL8HfxlER7Un70RR8,24406 +transformers/models/hunyuan_v1_dense/modular_hunyuan_v1_dense.py,sha256=Y5fzyH64s6lhvJRTBLE0Lz13qPwrwtl4wuw5nPUAgPM,7400 +transformers/models/hunyuan_v1_moe/__init__.py,sha256=JPxEpmnMsJGVMZzSx6_wGtDDkQD33aU1BEdPdXKzHUg,403 +transformers/models/hunyuan_v1_moe/__pycache__/__init__.cpython-310.pyc,, +transformers/models/hunyuan_v1_moe/__pycache__/configuration_hunyuan_v1_moe.cpython-310.pyc,, +transformers/models/hunyuan_v1_moe/__pycache__/modeling_hunyuan_v1_moe.cpython-310.pyc,, +transformers/models/hunyuan_v1_moe/__pycache__/modular_hunyuan_v1_moe.cpython-310.pyc,, +transformers/models/hunyuan_v1_moe/configuration_hunyuan_v1_moe.py,sha256=SBRpAm6bwsAaxcIL8dwclBlQasEvN580Ql5IMGIO1uU,10588 +transformers/models/hunyuan_v1_moe/modeling_hunyuan_v1_moe.py,sha256=_yMP5Uwb9vq-SWWefJ84euPFhmHCZWHazt46auikKuc,28776 +transformers/models/hunyuan_v1_moe/modular_hunyuan_v1_moe.py,sha256=QGbcJXQXRGbHF9FmVUJcEPBA-_lce-r5218xO0qu5LQ,9109 +transformers/models/ibert/__init__.py,sha256=UMTcE54y6O9UNF8l9VV2rrTlJSAHooxeNeHNzPSgr_E,991 +transformers/models/ibert/__pycache__/__init__.cpython-310.pyc,, +transformers/models/ibert/__pycache__/configuration_ibert.cpython-310.pyc,, +transformers/models/ibert/__pycache__/modeling_ibert.cpython-310.pyc,, +transformers/models/ibert/__pycache__/quant_modules.cpython-310.pyc,, +transformers/models/ibert/configuration_ibert.py,sha256=4PF-acAokMuDm9CdrhKH5LqhC3DyeZdl57qIAIKoCTQ,5810 +transformers/models/ibert/modeling_ibert.py,sha256=woU94KFptjqm44LGc179EQZfq3zC66Vci5Gu6k2xR_M,48804 +transformers/models/ibert/quant_modules.py,sha256=eQX3kw7hmlwleHnFmdDyliQpQkotzmaLpsFFb3KYcuU,30059 +transformers/models/idefics/__init__.py,sha256=mD0QaE4NyvNcabX_alDD8QSPpYMxbNZ3E6lJFOskjb0,1077 +transformers/models/idefics/__pycache__/__init__.cpython-310.pyc,, +transformers/models/idefics/__pycache__/configuration_idefics.cpython-310.pyc,, +transformers/models/idefics/__pycache__/image_processing_idefics.cpython-310.pyc,, +transformers/models/idefics/__pycache__/modeling_idefics.cpython-310.pyc,, +transformers/models/idefics/__pycache__/perceiver.cpython-310.pyc,, +transformers/models/idefics/__pycache__/processing_idefics.cpython-310.pyc,, +transformers/models/idefics/__pycache__/vision.cpython-310.pyc,, +transformers/models/idefics/configuration_idefics.py,sha256=LovrauA3mRc9bkFPDrAdxif3NDj1UmyLFYCOOsJRpHY,15274 +transformers/models/idefics/image_processing_idefics.py,sha256=wxv8wEIpGtWG2o0D88FzqGrMHjhLGc2Byc2GsfO1lRs,9772 +transformers/models/idefics/modeling_idefics.py,sha256=fJqSLtcZ6NuMhNETi6KYmURrqIZy7dw6_C08JSUo4Gs,57134 +transformers/models/idefics/perceiver.py,sha256=9rh7lz2ImHaRk2U3X_Mg-FoZXPtKzybt2hgAOJ9vX58,9394 +transformers/models/idefics/processing_idefics.py,sha256=JtlJ-2SmALq0Z9IXHRMldLvaQWqA7Xg98hquMqBk7to,16923 +transformers/models/idefics/vision.py,sha256=yZHGy0lqFuA5HdwgNnpISLtRGUV-C_NFNeM13V_VCR8,20867 +transformers/models/idefics2/__init__.py,sha256=YmU2OQi-BTXESv52a4jtTwWC2ingparNU4-rXVCPWzQ,1131 +transformers/models/idefics2/__pycache__/__init__.cpython-310.pyc,, +transformers/models/idefics2/__pycache__/configuration_idefics2.cpython-310.pyc,, +transformers/models/idefics2/__pycache__/image_processing_idefics2.cpython-310.pyc,, +transformers/models/idefics2/__pycache__/image_processing_idefics2_fast.cpython-310.pyc,, +transformers/models/idefics2/__pycache__/modeling_idefics2.cpython-310.pyc,, +transformers/models/idefics2/__pycache__/processing_idefics2.cpython-310.pyc,, +transformers/models/idefics2/configuration_idefics2.py,sha256=m1utlGsZMebf1TPkTk9sq246KIly9bTtfbiovoCHLOE,12124 +transformers/models/idefics2/image_processing_idefics2.py,sha256=dLAlhlaGDv4APCcWD8XgR-JJGLZEMyaVcFF6IVCaQuk,26505 +transformers/models/idefics2/image_processing_idefics2_fast.py,sha256=xMsn0PrHvoQ5q5SEVmn6-RgVitjNzSNXNsmPAuexwpk,11678 +transformers/models/idefics2/modeling_idefics2.py,sha256=A4eeO9P3YgfgkFlReZdgKA8TUQ_P5P-n-LoMOD8tL_c,50745 +transformers/models/idefics2/processing_idefics2.py,sha256=b6SmPArpHmJoNL-XagKJPgG8Nzl3Df4XjWfSfZyyjbY,8093 +transformers/models/idefics3/__init__.py,sha256=zLsOtUFi074lvfGbwZEMVSvV08TZgoq0DVhJJagYoRo,1131 +transformers/models/idefics3/__pycache__/__init__.cpython-310.pyc,, +transformers/models/idefics3/__pycache__/configuration_idefics3.cpython-310.pyc,, +transformers/models/idefics3/__pycache__/image_processing_idefics3.cpython-310.pyc,, +transformers/models/idefics3/__pycache__/image_processing_idefics3_fast.cpython-310.pyc,, +transformers/models/idefics3/__pycache__/modeling_idefics3.cpython-310.pyc,, +transformers/models/idefics3/__pycache__/processing_idefics3.cpython-310.pyc,, +transformers/models/idefics3/configuration_idefics3.py,sha256=ljACO4aq0bJ9EqPp_DDP__vsZYTkgbJMhxFGlycS4Hk,8439 +transformers/models/idefics3/image_processing_idefics3.py,sha256=AfwM3l7eMqkKqZrLzSEJ6LMTIzrG53xlUr013jKpwe8,44242 +transformers/models/idefics3/image_processing_idefics3_fast.py,sha256=Vk-1CsGOfh5WNNJgkjiRr8pZN_6tRHetwXtp9YLwu3k,23464 +transformers/models/idefics3/modeling_idefics3.py,sha256=Upid9i_unoT_ujm3xUdJc8gl7YV2oBvuF76jTUKw7YA,41821 +transformers/models/idefics3/processing_idefics3.py,sha256=wKEW8erWTB6i1ud11Sz7Ec3rmA-kbr1TwPLPG8IHvhU,14875 +transformers/models/ijepa/__init__.py,sha256=O0_Jqpy8kmorYC-x0QsoMYSHdqQt3E1j-UZGLQ9aCv0,991 +transformers/models/ijepa/__pycache__/__init__.cpython-310.pyc,, +transformers/models/ijepa/__pycache__/configuration_ijepa.cpython-310.pyc,, +transformers/models/ijepa/__pycache__/modeling_ijepa.cpython-310.pyc,, +transformers/models/ijepa/__pycache__/modular_ijepa.cpython-310.pyc,, +transformers/models/ijepa/configuration_ijepa.py,sha256=_FkXEDsARAt3Li8ScLgpTX38Xpjg4FuvIIpF6r4sM4w,5247 +transformers/models/ijepa/modeling_ijepa.py,sha256=FSg3y6crZAzcAKGmkx261fikllUl1BdMauFsgwZdWeo,20748 +transformers/models/ijepa/modular_ijepa.py,sha256=vvtZa--W223-VhvEoyyn1IuCIJonMa7OjXM1Kb-oOX0,7128 +transformers/models/imagegpt/__init__.py,sha256=NIc1rPRLS3e06c-xUW5Vk80IOSPK2L1ZrY_PJrHn1GY,1139 +transformers/models/imagegpt/__pycache__/__init__.cpython-310.pyc,, +transformers/models/imagegpt/__pycache__/configuration_imagegpt.cpython-310.pyc,, +transformers/models/imagegpt/__pycache__/image_processing_imagegpt.cpython-310.pyc,, +transformers/models/imagegpt/__pycache__/image_processing_imagegpt_fast.cpython-310.pyc,, +transformers/models/imagegpt/__pycache__/modeling_imagegpt.cpython-310.pyc,, +transformers/models/imagegpt/configuration_imagegpt.py,sha256=zx0hIezVdFXXgpS_aKFKh7xK92iHRKbvdc8F7f-1mas,6433 +transformers/models/imagegpt/image_processing_imagegpt.py,sha256=4tzRsDlCToSlRkTsB2S8oWKv5gmGtnZHaxR61sbFBig,15516 +transformers/models/imagegpt/image_processing_imagegpt_fast.py,sha256=d3gOg2ZS3hEj4qE5OZEJPwvKdxD90uygx-jq_xhvfXY,7221 +transformers/models/imagegpt/modeling_imagegpt.py,sha256=fdL-SPpierMHU7xo1LXIVaJIzhFuRHX77sj687a6zpw,37404 +transformers/models/informer/__init__.py,sha256=L-BwVQfdq5ve06VJJ-OnTh-m_YqSMNcpDQ1z6sbDtNI,997 +transformers/models/informer/__pycache__/__init__.cpython-310.pyc,, +transformers/models/informer/__pycache__/configuration_informer.cpython-310.pyc,, +transformers/models/informer/__pycache__/modeling_informer.cpython-310.pyc,, +transformers/models/informer/__pycache__/modular_informer.cpython-310.pyc,, +transformers/models/informer/configuration_informer.py,sha256=Jp661LZdCGbnw3-qJgf_Y-F7W1OyRAupSKW26jaWVsI,12413 +transformers/models/informer/modeling_informer.py,sha256=LU99mvazu8LxK4yN9peRsEKZsQYs3nJeRvMPIwn4g3E,95444 +transformers/models/informer/modular_informer.py,sha256=-n142Khr8hGmsOkyN56PBV3Z4XjhJbgCooroAeXuq1k,41053 +transformers/models/instructblip/__init__.py,sha256=gI7F0N1dRSYdZtTumtuoPcIJcuBI8PO4DEOQS4_nWuc,1048 +transformers/models/instructblip/__pycache__/__init__.cpython-310.pyc,, +transformers/models/instructblip/__pycache__/configuration_instructblip.cpython-310.pyc,, +transformers/models/instructblip/__pycache__/modeling_instructblip.cpython-310.pyc,, +transformers/models/instructblip/__pycache__/processing_instructblip.cpython-310.pyc,, +transformers/models/instructblip/configuration_instructblip.py,sha256=ddEcdgwFGtt3SjjKLmbYniAL9DoCuOuKiEm9ZDufX6A,14703 +transformers/models/instructblip/modeling_instructblip.py,sha256=Iqf6qdAeiLqmW0_nhS7MNyclL4aXRbbX-Gt4wOjfQaA,63768 +transformers/models/instructblip/processing_instructblip.py,sha256=afU05hN3vHDxe8hW8TpYm8NsHHqIdGOxfBnRMDlw7IU,5403 +transformers/models/instructblipvideo/__init__.py,sha256=sgK7MEwrqKB6mQyEvhxcgOQc_OAtMDc9tAZqKF0sxfM,1171 +transformers/models/instructblipvideo/__pycache__/__init__.cpython-310.pyc,, +transformers/models/instructblipvideo/__pycache__/configuration_instructblipvideo.cpython-310.pyc,, +transformers/models/instructblipvideo/__pycache__/modeling_instructblipvideo.cpython-310.pyc,, +transformers/models/instructblipvideo/__pycache__/modular_instructblipvideo.cpython-310.pyc,, +transformers/models/instructblipvideo/__pycache__/processing_instructblipvideo.cpython-310.pyc,, +transformers/models/instructblipvideo/__pycache__/video_processing_instructblipvideo.cpython-310.pyc,, +transformers/models/instructblipvideo/configuration_instructblipvideo.py,sha256=G3hspUpP1MHuRTcUzvxbKWpl4ObuHlIQKT9_fe8n1V8,15826 +transformers/models/instructblipvideo/modeling_instructblipvideo.py,sha256=oFi2ThN5oTrQH3i5UjDkewpSPHnSMvLu8uYIMRPMxuY,66205 +transformers/models/instructblipvideo/modular_instructblipvideo.py,sha256=jqiDWERA6tw6z7lyeeMzO9Ia0qPyIwAlODNvUjOBHds,27631 +transformers/models/instructblipvideo/processing_instructblipvideo.py,sha256=Yjx3AOxIIOO0Xvl9oQGnFxFeNXhzUqsTBNtCYN0D3NA,6953 +transformers/models/instructblipvideo/video_processing_instructblipvideo.py,sha256=qaPXSa8i7SiN-SFxtf3wGQc3JlE003ijSx92p_yTHj0,3611 +transformers/models/internvl/__init__.py,sha256=tNXeZ8TIWlY70CelRiihyPOudKQtRBZp-c9WqglJ8ss,1081 +transformers/models/internvl/__pycache__/__init__.cpython-310.pyc,, +transformers/models/internvl/__pycache__/configuration_internvl.cpython-310.pyc,, +transformers/models/internvl/__pycache__/modeling_internvl.cpython-310.pyc,, +transformers/models/internvl/__pycache__/modular_internvl.cpython-310.pyc,, +transformers/models/internvl/__pycache__/processing_internvl.cpython-310.pyc,, +transformers/models/internvl/__pycache__/video_processing_internvl.cpython-310.pyc,, +transformers/models/internvl/configuration_internvl.py,sha256=ok9uXE_F7Meoy-wFVrVn69BYa7AqOEvmhs-NX3f0tD8,10812 +transformers/models/internvl/modeling_internvl.py,sha256=F16Q0BJK2ImPL6ve2uMcrIHtBjOxCBit3ovVgCYw7pY,38137 +transformers/models/internvl/modular_internvl.py,sha256=WPJB2PtbYd0LO2a4vSqLu3RQC2GavE81WeUWbxZPmH8,25332 +transformers/models/internvl/processing_internvl.py,sha256=2b1v8nUlRrbUEEZqJqUtisx7FQnXQsE66_8xLtzmV5U,12777 +transformers/models/internvl/video_processing_internvl.py,sha256=B2z0lpywKF9SUJNnm2ARVEfzpOMhKK8taWOhK8MeAXs,6385 +transformers/models/jais2/__init__.py,sha256=LVvqkaW19UQe2FBjDw020iqwElvB1n4uqk7Snf_gcac,991 +transformers/models/jais2/__pycache__/__init__.cpython-310.pyc,, +transformers/models/jais2/__pycache__/configuration_jais2.cpython-310.pyc,, +transformers/models/jais2/__pycache__/modeling_jais2.cpython-310.pyc,, +transformers/models/jais2/__pycache__/modular_jais2.cpython-310.pyc,, +transformers/models/jais2/configuration_jais2.py,sha256=fIuPFqBpoZv5zwd-5FcflRBgWIRk4d12HL-8xpZsIa4,7115 +transformers/models/jais2/modeling_jais2.py,sha256=BoRHlnF0-FGBkJEPVqM1yyNsAoQ7eBXSd-ZeSsNyPNg,20691 +transformers/models/jais2/modular_jais2.py,sha256=KBrWCvsULsjRtsnC8y_3PmH10pos9yhsWyjfTtQUOVA,7733 +transformers/models/jamba/__init__.py,sha256=zN7Rmr--d5GCEJzMA7gxIz-BYFydPN3cyuif85YU0Fk,991 +transformers/models/jamba/__pycache__/__init__.cpython-310.pyc,, +transformers/models/jamba/__pycache__/configuration_jamba.cpython-310.pyc,, +transformers/models/jamba/__pycache__/modeling_jamba.cpython-310.pyc,, +transformers/models/jamba/__pycache__/modular_jamba.cpython-310.pyc,, +transformers/models/jamba/configuration_jamba.py,sha256=Q4WHVy0LunqjO8BQhCII0kImRRy0CojedIDMYFpmjaU,10937 +transformers/models/jamba/modeling_jamba.py,sha256=ecDv7qdB9kIn3Grt2zJ_c7_L2buiOFly6zTgRKdWc_A,49262 +transformers/models/jamba/modular_jamba.py,sha256=F0ka0uV-Lc2cuL7W38GwxEGOBC3w3OTpIY7keDPOqPw,35852 +transformers/models/janus/__init__.py,sha256=rTnJnHMmmoPxIVasip4sdS5aZ1wvetOtZUobIMYMHX4,1132 +transformers/models/janus/__pycache__/__init__.cpython-310.pyc,, +transformers/models/janus/__pycache__/configuration_janus.cpython-310.pyc,, +transformers/models/janus/__pycache__/image_processing_janus.cpython-310.pyc,, +transformers/models/janus/__pycache__/image_processing_janus_fast.cpython-310.pyc,, +transformers/models/janus/__pycache__/modeling_janus.cpython-310.pyc,, +transformers/models/janus/__pycache__/modular_janus.cpython-310.pyc,, +transformers/models/janus/__pycache__/processing_janus.cpython-310.pyc,, +transformers/models/janus/configuration_janus.py,sha256=iba9lsTuJB3tGgFoao1P_Kpt-zfPdsOkOTFFcvulves,14893 +transformers/models/janus/image_processing_janus.py,sha256=4kJvl3m9KTX8TDw1QaOLEJgoTKNL1m2YadgCN-n6HSw,26116 +transformers/models/janus/image_processing_janus_fast.py,sha256=djbsj7kyOqeC8_iE_-cyHAaBH4MuDr8D8Co8N4d4OmQ,8707 +transformers/models/janus/modeling_janus.py,sha256=cNC1YfzvdfA6MWsIe7X7GMIo1OjoHx5VQ24k8juiMEw,59402 +transformers/models/janus/modular_janus.py,sha256=esC-UdR0sZ90BO_NEBUjM81TKNYlIJr2Cdi2I1KgI-c,79439 +transformers/models/janus/processing_janus.py,sha256=Xyjb4fM2cvj39wqkVnRO8wgyxEdtS-E9OjKokEfaQVk,7227 +transformers/models/jetmoe/__init__.py,sha256=zhqtP2ZDCCl3Fp3VBnnuaA044Ztbh7fsUKogAKABOt0,993 +transformers/models/jetmoe/__pycache__/__init__.cpython-310.pyc,, +transformers/models/jetmoe/__pycache__/configuration_jetmoe.cpython-310.pyc,, +transformers/models/jetmoe/__pycache__/modeling_jetmoe.cpython-310.pyc,, +transformers/models/jetmoe/__pycache__/modular_jetmoe.cpython-310.pyc,, +transformers/models/jetmoe/configuration_jetmoe.py,sha256=XJAmWJQaYkQDu4jLl-tcPexewr2wd7Z14M3tRrdyPK4,7546 +transformers/models/jetmoe/modeling_jetmoe.py,sha256=xqvcIAsE5sm_VNGeLYe5CXUogirQOgKoaIZ34yc9Nw4,35910 +transformers/models/jetmoe/modular_jetmoe.py,sha256=oXSWfzpyanPtn9YtDn9L8t4CrAn3H2tWynyEWs-iIk8,24518 +transformers/models/kosmos2/__init__.py,sha256=Ow8cLelhxl6fm5XvXzNQtPLt1xjIdVmGUwz5NoVVVto,1033 +transformers/models/kosmos2/__pycache__/__init__.cpython-310.pyc,, +transformers/models/kosmos2/__pycache__/configuration_kosmos2.cpython-310.pyc,, +transformers/models/kosmos2/__pycache__/modeling_kosmos2.cpython-310.pyc,, +transformers/models/kosmos2/__pycache__/processing_kosmos2.cpython-310.pyc,, +transformers/models/kosmos2/configuration_kosmos2.py,sha256=Z4IRDMGyqDlHF1c89sBNwzfBdicTuEp9S3q0XZBApKo,12316 +transformers/models/kosmos2/modeling_kosmos2.py,sha256=ahAbi8JVoNC59_BDNnOf1sStsS6e8yMlKv5FIhCObrc,80272 +transformers/models/kosmos2/processing_kosmos2.py,sha256=dZMtfTH5Xj-skpD1YgtEgXQ1YpohcnTRVUAerepGr9A,29686 +transformers/models/kosmos2_5/__init__.py,sha256=Ry_vGQuW5FUZfpqseOHgHpb9Qivx1rMLHxq15iNGJVU,1164 +transformers/models/kosmos2_5/__pycache__/__init__.cpython-310.pyc,, +transformers/models/kosmos2_5/__pycache__/configuration_kosmos2_5.cpython-310.pyc,, +transformers/models/kosmos2_5/__pycache__/image_processing_kosmos2_5.cpython-310.pyc,, +transformers/models/kosmos2_5/__pycache__/image_processing_kosmos2_5_fast.cpython-310.pyc,, +transformers/models/kosmos2_5/__pycache__/modeling_kosmos2_5.cpython-310.pyc,, +transformers/models/kosmos2_5/__pycache__/processing_kosmos2_5.cpython-310.pyc,, +transformers/models/kosmos2_5/configuration_kosmos2_5.py,sha256=fdQv9ZhuHhyMtrt4KTKJ21xCFWruK469AoowkNXMz_g,12010 +transformers/models/kosmos2_5/image_processing_kosmos2_5.py,sha256=hWo56kUZF5mCLaEk31Uzqe4_Q-DXhhkTqRoQDy1F-go,14856 +transformers/models/kosmos2_5/image_processing_kosmos2_5_fast.py,sha256=yOr86Y8gPUICWgGVAOSFnxglEx1iFnDHkBht5UUtqMs,10925 +transformers/models/kosmos2_5/modeling_kosmos2_5.py,sha256=6WY9dnThrxfddDetjg7E5jAtj7hvmLE_bwUZFZ-MuHM,76366 +transformers/models/kosmos2_5/processing_kosmos2_5.py,sha256=JGMgmk_AEwP4P2Lbcixwper8irDA_em4PdQp4xOwSIw,5022 +transformers/models/kyutai_speech_to_text/__init__.py,sha256=KxatXD7pSOmwZWzs7nFOXG9Hc2wxaAS3CYwxg54lq9g,1135 +transformers/models/kyutai_speech_to_text/__pycache__/__init__.cpython-310.pyc,, +transformers/models/kyutai_speech_to_text/__pycache__/configuration_kyutai_speech_to_text.cpython-310.pyc,, +transformers/models/kyutai_speech_to_text/__pycache__/feature_extraction_kyutai_speech_to_text.cpython-310.pyc,, +transformers/models/kyutai_speech_to_text/__pycache__/modeling_kyutai_speech_to_text.cpython-310.pyc,, +transformers/models/kyutai_speech_to_text/__pycache__/modular_kyutai_speech_to_text.cpython-310.pyc,, +transformers/models/kyutai_speech_to_text/__pycache__/processing_kyutai_speech_to_text.cpython-310.pyc,, +transformers/models/kyutai_speech_to_text/configuration_kyutai_speech_to_text.py,sha256=WM-Xlk3t1FJIHswr2ENjeU7fjuJhJIWPL_qy9sK46tg,9843 +transformers/models/kyutai_speech_to_text/feature_extraction_kyutai_speech_to_text.py,sha256=jwuZlFRJXx7ugj587aj1Hy2HcFzT0rQesJkd9piw36A,11643 +transformers/models/kyutai_speech_to_text/modeling_kyutai_speech_to_text.py,sha256=vCIeZf2fW_eB-JXmDYYfapWZpffnnPnTvafYMIesse4,56141 +transformers/models/kyutai_speech_to_text/modular_kyutai_speech_to_text.py,sha256=DC9e40dJZzGtWRABsW5Dajf0UF7E6FA1DIN7Fmeb26Q,23845 +transformers/models/kyutai_speech_to_text/processing_kyutai_speech_to_text.py,sha256=4ytDDKi8Hm7naE_eOdlJzWs44n3ls2MNNi4so6pzS2Q,1222 +transformers/models/lasr/__init__.py,sha256=UbsmofJn1eRFzyEA05Ln2QkBbfutcUmuFy43LhASHGA,1069 +transformers/models/lasr/__pycache__/__init__.cpython-310.pyc,, +transformers/models/lasr/__pycache__/configuration_lasr.cpython-310.pyc,, +transformers/models/lasr/__pycache__/feature_extraction_lasr.cpython-310.pyc,, +transformers/models/lasr/__pycache__/modeling_lasr.cpython-310.pyc,, +transformers/models/lasr/__pycache__/modular_lasr.cpython-310.pyc,, +transformers/models/lasr/__pycache__/processing_lasr.cpython-310.pyc,, +transformers/models/lasr/__pycache__/tokenization_lasr.cpython-310.pyc,, +transformers/models/lasr/configuration_lasr.py,sha256=jlYf1rmD9o_Knh8rvSpyfLEpDXPDY9e9LAhcVR7n5sk,12064 +transformers/models/lasr/feature_extraction_lasr.py,sha256=p8UAKIOxI2PsufW64Vdm03aNO1JjTaQNeu-dpUGhfWA,12687 +transformers/models/lasr/modeling_lasr.py,sha256=R3hUZXxqttljl9pED57oOTP8XknWHyxIujDAjQ6uCLU,31096 +transformers/models/lasr/modular_lasr.py,sha256=UWJIAMefu7uLdqWQ3qFcAqCO1kofP9q1sAoZIE6ENMQ,25948 +transformers/models/lasr/processing_lasr.py,sha256=5523eQzqjXvv72sZNt5BMFr0MG22G5lbanBlRPHDn7Y,4494 +transformers/models/lasr/tokenization_lasr.py,sha256=LNSDQPmRIuXu33pm9gcgtPK7u-Donam6TZ5932ucC78,8081 +transformers/models/layoutlm/__init__.py,sha256=CXQ3kNqiSnGoJfjGmZnCsZWFljg1MYZVKSGXtSRpPyg,1153 +transformers/models/layoutlm/__pycache__/__init__.cpython-310.pyc,, +transformers/models/layoutlm/__pycache__/configuration_layoutlm.cpython-310.pyc,, +transformers/models/layoutlm/__pycache__/modeling_layoutlm.cpython-310.pyc,, +transformers/models/layoutlm/configuration_layoutlm.py,sha256=Z_DFyI8LfUi76ll1NsvF89U5_lrlwNHBHFX4egQV8HQ,6319 +transformers/models/layoutlm/modeling_layoutlm.py,sha256=WASmZrLLxl0So3oulz99rfpaiHET_9cZk1Yl99PT0YQ,44004 +transformers/models/layoutlmv2/__init__.py,sha256=a7lJ1uczcz0ea-KPeNk_S6JyNTPNKW6d39qneREmUTk,1233 +transformers/models/layoutlmv2/__pycache__/__init__.cpython-310.pyc,, +transformers/models/layoutlmv2/__pycache__/configuration_layoutlmv2.cpython-310.pyc,, +transformers/models/layoutlmv2/__pycache__/image_processing_layoutlmv2.cpython-310.pyc,, +transformers/models/layoutlmv2/__pycache__/image_processing_layoutlmv2_fast.cpython-310.pyc,, +transformers/models/layoutlmv2/__pycache__/modeling_layoutlmv2.cpython-310.pyc,, +transformers/models/layoutlmv2/__pycache__/processing_layoutlmv2.cpython-310.pyc,, +transformers/models/layoutlmv2/__pycache__/tokenization_layoutlmv2.cpython-310.pyc,, +transformers/models/layoutlmv2/configuration_layoutlmv2.py,sha256=ogZgbdspKiurk4Fhtf4V9sCfFlZgeKwtKTn2dW9mdYc,11112 +transformers/models/layoutlmv2/image_processing_layoutlmv2.py,sha256=z4ztDkVewClX3nZe0NdsQkkT4Q98kjTQF-_jxCFri9o,14241 +transformers/models/layoutlmv2/image_processing_layoutlmv2_fast.py,sha256=FefKs0bhIn_PeRlJfi7DPoapoH0-P0v-IePxeOVtQkw,4434 +transformers/models/layoutlmv2/modeling_layoutlmv2.py,sha256=7PpSKuzEfYZlSCFZhCGcsFgXQ7wrbIPBI_qW3KuVdlE,60774 +transformers/models/layoutlmv2/processing_layoutlmv2.py,sha256=TIowT2fNZDsaTRFVmtaCSX4D23LUw2n_cDr7xyY7sig,5316 +transformers/models/layoutlmv2/tokenization_layoutlmv2.py,sha256=PYbYwyLREzS3YX3C1QS7iiq5i2Owks7wEDH3aFusj34,42661 +transformers/models/layoutlmv3/__init__.py,sha256=bgVnOOaQ4iwNhUFh6XgKWEc7NJ-EP_26AsJl2uH-_E4,1233 +transformers/models/layoutlmv3/__pycache__/__init__.cpython-310.pyc,, +transformers/models/layoutlmv3/__pycache__/configuration_layoutlmv3.cpython-310.pyc,, +transformers/models/layoutlmv3/__pycache__/image_processing_layoutlmv3.cpython-310.pyc,, +transformers/models/layoutlmv3/__pycache__/image_processing_layoutlmv3_fast.cpython-310.pyc,, +transformers/models/layoutlmv3/__pycache__/modeling_layoutlmv3.cpython-310.pyc,, +transformers/models/layoutlmv3/__pycache__/processing_layoutlmv3.cpython-310.pyc,, +transformers/models/layoutlmv3/__pycache__/tokenization_layoutlmv3.cpython-310.pyc,, +transformers/models/layoutlmv3/configuration_layoutlmv3.py,sha256=H7s9dWEDywbCEqm5rtTw_xg9faGcpkBw28fsbpwP7Go,8460 +transformers/models/layoutlmv3/image_processing_layoutlmv3.py,sha256=LE8uZxMzepeSSy2K_HH3Rjd4MqrxipR5m7FdQ3XKdSw,19353 +transformers/models/layoutlmv3/image_processing_layoutlmv3_fast.py,sha256=gH1qG-AH6zEgSb8Dcaq3fCnQW1XyaZgcQRfE7PVmT7o,5003 +transformers/models/layoutlmv3/modeling_layoutlmv3.py,sha256=pRijVUlaM_BSX_DjwgepX7xnMotlUFd3KCkVX1krkKk,52299 +transformers/models/layoutlmv3/processing_layoutlmv3.py,sha256=rMkBG1RLG4OvWbyhl5tVddhS0bt3G9ShwUkwVR5NSOY,5097 +transformers/models/layoutlmv3/tokenization_layoutlmv3.py,sha256=ZDTROT5oDFfLQ6cVMFAIeP2U-aVUDfiFWQFPQ1yAuJE,42660 +transformers/models/layoutxlm/__init__.py,sha256=G7vpZzVESxlNUZ7PtI8z28ng6MalHJAXFViKeoFSkCA,1043 +transformers/models/layoutxlm/__pycache__/__init__.cpython-310.pyc,, +transformers/models/layoutxlm/__pycache__/configuration_layoutxlm.cpython-310.pyc,, +transformers/models/layoutxlm/__pycache__/modular_layoutxlm.cpython-310.pyc,, +transformers/models/layoutxlm/__pycache__/processing_layoutxlm.cpython-310.pyc,, +transformers/models/layoutxlm/__pycache__/tokenization_layoutxlm.cpython-310.pyc,, +transformers/models/layoutxlm/configuration_layoutxlm.py,sha256=le5Valj8b0aMMj2g-RAbJxwHl8xJepRLnKT8bQYavTQ,11801 +transformers/models/layoutxlm/modular_layoutxlm.py,sha256=UYbSsoU2jezheCSpPuG4iuLknunD9Xsi4TLS50TWDco,6425 +transformers/models/layoutxlm/processing_layoutxlm.py,sha256=ibbzcqmbnKb4mUSVMZjY-AfJ7ZfxuiEVh7zTR1ABBNo,5294 +transformers/models/layoutxlm/tokenization_layoutxlm.py,sha256=u6W_Tmk83PS5KI5rozEAJjt9a1sMgFEYijuZpH3k10I,46151 +transformers/models/led/__init__.py,sha256=Zsd1RB7usdzST298N6SYV9M-3tC1W6Z8d4k-xwF-Vm8,1067 +transformers/models/led/__pycache__/__init__.cpython-310.pyc,, +transformers/models/led/__pycache__/configuration_led.cpython-310.pyc,, +transformers/models/led/__pycache__/modeling_led.cpython-310.pyc,, +transformers/models/led/configuration_led.py,sha256=8Qrq_bHicXzs-2t_-8PwcnVOoMfMjj-Vn7FsxI0YJEA,7467 +transformers/models/led/modeling_led.py,sha256=iLCPm1-ifR2bQeoz3sdtzKZpTEhNNyrNBYfkztoYVG4,107794 +transformers/models/levit/__init__.py,sha256=acEjEeDtpQ9q3a-hf90z6TZ0js04BtZvbCcn4HGWCyk,1124 +transformers/models/levit/__pycache__/__init__.cpython-310.pyc,, +transformers/models/levit/__pycache__/configuration_levit.cpython-310.pyc,, +transformers/models/levit/__pycache__/image_processing_levit.cpython-310.pyc,, +transformers/models/levit/__pycache__/image_processing_levit_fast.cpython-310.pyc,, +transformers/models/levit/__pycache__/modeling_levit.cpython-310.pyc,, +transformers/models/levit/configuration_levit.py,sha256=Zzy87xKwOp97lfYhH-p1FAdRfgk5f-P9yp_ovbw3WAA,5132 +transformers/models/levit/image_processing_levit.py,sha256=W17jvj2W_PNaQ9BfZcaDAKHSet14c71LjNeXS1fXb18,16325 +transformers/models/levit/image_processing_levit_fast.py,sha256=lPgGEtvBCuNekwmezoNzrGn2ToQ5KCleTLbimhqUQbs,3721 +transformers/models/levit/modeling_levit.py,sha256=Xx_63PQA7LZQxgZpRNSd9QP5tLmZxJLAoM60iX6sDi4,25355 +transformers/models/lfm2/__init__.py,sha256=9fNMRtqveDp18iRtUjNqCu0XELuvwJOmizUyI1h0zHw,989 +transformers/models/lfm2/__pycache__/__init__.cpython-310.pyc,, +transformers/models/lfm2/__pycache__/configuration_lfm2.cpython-310.pyc,, +transformers/models/lfm2/__pycache__/modeling_lfm2.cpython-310.pyc,, +transformers/models/lfm2/__pycache__/modular_lfm2.cpython-310.pyc,, +transformers/models/lfm2/configuration_lfm2.py,sha256=KPex3cD3Ljv2SoOJMdb7McKfIuheRp9bslMv1wvYEm4,8214 +transformers/models/lfm2/modeling_lfm2.py,sha256=2cCsMHabiTlANbv4wtDQAKE-zAw1uj8Bv-jBIPkyNEU,32731 +transformers/models/lfm2/modular_lfm2.py,sha256=3-J3I8Plf1Az2i5GhjGLse_z4cciIrKvAHpQMpchTjs,20058 +transformers/models/lfm2_moe/__init__.py,sha256=_yqIDhEkNsZIDJ1IlpVkA9Lvnlby05bpiPZvZid9na8,998 +transformers/models/lfm2_moe/__pycache__/__init__.cpython-310.pyc,, +transformers/models/lfm2_moe/__pycache__/configuration_lfm2_moe.cpython-310.pyc,, +transformers/models/lfm2_moe/__pycache__/modeling_lfm2_moe.cpython-310.pyc,, +transformers/models/lfm2_moe/__pycache__/modular_lfm2_moe.cpython-310.pyc,, +transformers/models/lfm2_moe/configuration_lfm2_moe.py,sha256=DU3jX4a-IyAbVAfGuM0sb9s2W2tv99QNr5WG7tTsr_4,8384 +transformers/models/lfm2_moe/modeling_lfm2_moe.py,sha256=OWWZCTnbB1s17xyL8mHUPSwzaBDEtqXynNZv7KypdN4,37167 +transformers/models/lfm2_moe/modular_lfm2_moe.py,sha256=3hbnRAYirfVFQxHAvzjsiV-FRh99XTzmpjysPDqMo18,8764 +transformers/models/lfm2_vl/__init__.py,sha256=qKhv0-rYp9emO4HCSVPOpPCB8hUy62P2v2rYjkBeTAI,1082 +transformers/models/lfm2_vl/__pycache__/__init__.cpython-310.pyc,, +transformers/models/lfm2_vl/__pycache__/configuration_lfm2_vl.cpython-310.pyc,, +transformers/models/lfm2_vl/__pycache__/image_processing_lfm2_vl_fast.cpython-310.pyc,, +transformers/models/lfm2_vl/__pycache__/modeling_lfm2_vl.cpython-310.pyc,, +transformers/models/lfm2_vl/__pycache__/modular_lfm2_vl.cpython-310.pyc,, +transformers/models/lfm2_vl/__pycache__/processing_lfm2_vl.cpython-310.pyc,, +transformers/models/lfm2_vl/configuration_lfm2_vl.py,sha256=b-HmIVvjUsof02KsrhqaruJi-m0PJek6b2Q7DbK4VQ4,4339 +transformers/models/lfm2_vl/image_processing_lfm2_vl_fast.py,sha256=zL1aWVqtWt4ruWJGZlHBlajQPjILwJeO-z_qCKPJMJs,23597 +transformers/models/lfm2_vl/modeling_lfm2_vl.py,sha256=ZhzYjzXmFU8dIN6OHqnMjEK--mUjTss2MEuvH-3Rjuc,21032 +transformers/models/lfm2_vl/modular_lfm2_vl.py,sha256=P1RN91NsDHzDUX19Fm2aRSXU4ypFaQ8KHpw4R-qw4A4,14944 +transformers/models/lfm2_vl/processing_lfm2_vl.py,sha256=TcOxkkO_pDXn4sPAOJ22bfUDai8t2zd20KXAFPS_FJw,11061 +transformers/models/lightglue/__init__.py,sha256=EI3kV4B5hnpUdzpP3PylbMIWX3Na80-8R0-tK1l_9g4,1096 +transformers/models/lightglue/__pycache__/__init__.cpython-310.pyc,, +transformers/models/lightglue/__pycache__/configuration_lightglue.cpython-310.pyc,, +transformers/models/lightglue/__pycache__/image_processing_lightglue.cpython-310.pyc,, +transformers/models/lightglue/__pycache__/image_processing_lightglue_fast.cpython-310.pyc,, +transformers/models/lightglue/__pycache__/modeling_lightglue.cpython-310.pyc,, +transformers/models/lightglue/__pycache__/modular_lightglue.cpython-310.pyc,, +transformers/models/lightglue/configuration_lightglue.py,sha256=_JVnWv0KcM8oKpUWMJs0bpLM-XWMCUgWi8gwr6oTTBE,8135 +transformers/models/lightglue/image_processing_lightglue.py,sha256=mdQpPkzN53Faq0JZ4sQ-VU0cB-qoQpGp0VWaKF2AfG0,22104 +transformers/models/lightglue/image_processing_lightglue_fast.py,sha256=5zDA4TD0Zhxpw4RcNB7oAPjNtCru_p-Q1LKH_zVS5uk,13415 +transformers/models/lightglue/modeling_lightglue.py,sha256=cfc3uKc1pmKC8u6tbCMAZfabpFq5hCLAGPpnsNDxDgg,43278 +transformers/models/lightglue/modular_lightglue.py,sha256=DI9X7IjSTWX3cGqpRUdP3t15v8zpXPND0KJKXwZZXFI,45877 +transformers/models/lighton_ocr/__init__.py,sha256=AuPKc-HKbs3mL5TQMIXjGEKFSgmqiesmHdh_vz1ufgA,1071 +transformers/models/lighton_ocr/__pycache__/__init__.cpython-310.pyc,, +transformers/models/lighton_ocr/__pycache__/configuration_lighton_ocr.cpython-310.pyc,, +transformers/models/lighton_ocr/__pycache__/modeling_lighton_ocr.cpython-310.pyc,, +transformers/models/lighton_ocr/__pycache__/modular_lighton_ocr.cpython-310.pyc,, +transformers/models/lighton_ocr/__pycache__/processing_lighton_ocr.cpython-310.pyc,, +transformers/models/lighton_ocr/configuration_lighton_ocr.py,sha256=543HtJ22QU7r_Ys1WsZuoxq_ny2xjtedZtY_ECZzNBA,5817 +transformers/models/lighton_ocr/modeling_lighton_ocr.py,sha256=DMVTJeeVS-olmO1B27e8ej2iN7MpQFD_aj4SSAUjzdI,20806 +transformers/models/lighton_ocr/modular_lighton_ocr.py,sha256=OMDinUinLqvrZ4o1-EEK7prBqllt3jCaK9VpzI-UsMo,16992 +transformers/models/lighton_ocr/processing_lighton_ocr.py,sha256=geRPzTsqs-3sofqMaSfoplga6QZaf0HVnW3C20qxCVo,10514 +transformers/models/lilt/__init__.py,sha256=9XEq7kJwN0mKO469mR0mtlRUdljjq7V80gejpqb59K0,989 +transformers/models/lilt/__pycache__/__init__.cpython-310.pyc,, +transformers/models/lilt/__pycache__/configuration_lilt.cpython-310.pyc,, +transformers/models/lilt/__pycache__/modeling_lilt.cpython-310.pyc,, +transformers/models/lilt/configuration_lilt.py,sha256=El4nERIMVPaq7iHrRG5dv4I4ZSwMj9IV_NZ0WhUy4Jo,6107 +transformers/models/lilt/modeling_lilt.py,sha256=l2A_ji3nb7JTMZ7RHDgc1E9C_nbKt1dxw_MjY696WwI,42307 +transformers/models/llama/__init__.py,sha256=LudwEMppX6Bp64aF29OM0FLgQ8KOlJwqvA0Uhcax-cM,1029 +transformers/models/llama/__pycache__/__init__.cpython-310.pyc,, +transformers/models/llama/__pycache__/configuration_llama.cpython-310.pyc,, +transformers/models/llama/__pycache__/modeling_llama.cpython-310.pyc,, +transformers/models/llama/__pycache__/tokenization_llama.cpython-310.pyc,, +transformers/models/llama/configuration_llama.py,sha256=gbpKEOcuBGr4zB4yRZFEFUqbISI3lF4u3ETB10iVT44,9230 +transformers/models/llama/modeling_llama.py,sha256=xEy3u9gtYSirR12AH_PjrqypNW-XWhdYuqeIkPzhnnc,21837 +transformers/models/llama/tokenization_llama.py,sha256=zPlApP7BmmzCAHnKz2X-kWGma1jujUaaQ23lOihfysg,6346 +transformers/models/llama4/__init__.py,sha256=YLpUGkKivYWky6rr715H2yMb9fCPr_3AV8OwWd2mrpA,1078 +transformers/models/llama4/__pycache__/__init__.cpython-310.pyc,, +transformers/models/llama4/__pycache__/configuration_llama4.cpython-310.pyc,, +transformers/models/llama4/__pycache__/image_processing_llama4_fast.cpython-310.pyc,, +transformers/models/llama4/__pycache__/modeling_llama4.cpython-310.pyc,, +transformers/models/llama4/__pycache__/processing_llama4.cpython-310.pyc,, +transformers/models/llama4/configuration_llama4.py,sha256=H55rb0u7piXwbx3iOksBqe5EuEyA22oPMkmJPiW6YLo,22254 +transformers/models/llama4/image_processing_llama4_fast.py,sha256=8ZAOAVrqtfN4G94bzRNgAjfzO_kfEzGth61uZccoeUc,17001 +transformers/models/llama4/modeling_llama4.py,sha256=IlpTa5yBqi_1LQ_TwjzF8qSKDQI3_OMboLo9KQhGJxY,60033 +transformers/models/llama4/processing_llama4.py,sha256=oCaHuMVqg45Nfz-3NPBhTZlxdD7gL9crBT805oBe0ok,14177 +transformers/models/llava/__init__.py,sha256=h7TDiwhtiqDQbay9v760sbmBGM6yWs3J1tmnIr3PCys,1074 +transformers/models/llava/__pycache__/__init__.cpython-310.pyc,, +transformers/models/llava/__pycache__/configuration_llava.cpython-310.pyc,, +transformers/models/llava/__pycache__/image_processing_llava.cpython-310.pyc,, +transformers/models/llava/__pycache__/image_processing_llava_fast.cpython-310.pyc,, +transformers/models/llava/__pycache__/modeling_llava.cpython-310.pyc,, +transformers/models/llava/__pycache__/processing_llava.cpython-310.pyc,, +transformers/models/llava/configuration_llava.py,sha256=--Tvme4j6pAWcJI15aIjFPGCl4G8ueHpDCStjmhL7UY,6353 +transformers/models/llava/image_processing_llava.py,sha256=87R3gDUTyWprS5UCGKQjb2-QMz1zN6T6cwPm4xZQyZk,20812 +transformers/models/llava/image_processing_llava_fast.py,sha256=f2miX838xvCJEYPIZ1gxjZ-OAuu_31Qvw4ni99h5JSs,6072 +transformers/models/llava/modeling_llava.py,sha256=n-py1VlyVnV1aPi8GXQMxy5nSaBKIuavTH3y7y0o7Ic,18780 +transformers/models/llava/processing_llava.py,sha256=5dxlcEgfPP6WPa-dGus_Qhy6QxVjikYlQNOa7P1dlTQ,7447 +transformers/models/llava_next/__init__.py,sha256=gyT3qcEjuxecgCiFoQoz-tf10ShqzfOL8IzPOhpjfto,1141 +transformers/models/llava_next/__pycache__/__init__.cpython-310.pyc,, +transformers/models/llava_next/__pycache__/configuration_llava_next.cpython-310.pyc,, +transformers/models/llava_next/__pycache__/image_processing_llava_next.cpython-310.pyc,, +transformers/models/llava_next/__pycache__/image_processing_llava_next_fast.cpython-310.pyc,, +transformers/models/llava_next/__pycache__/modeling_llava_next.cpython-310.pyc,, +transformers/models/llava_next/__pycache__/processing_llava_next.cpython-310.pyc,, +transformers/models/llava_next/configuration_llava_next.py,sha256=_rjez8bcHNQd0OzgOZS3cdkM14Om5_ij5r6PaBqRVcM,6775 +transformers/models/llava_next/image_processing_llava_next.py,sha256=2HB1YEnlUibVlwsSSkTtvaCgAmYl9A22MmbpWai3tos,35817 +transformers/models/llava_next/image_processing_llava_next_fast.py,sha256=YSmorIPpi-DmlPlT6VEZFSqruBeKHUSz72eY4fxvju4,10102 +transformers/models/llava_next/modeling_llava_next.py,sha256=66El0sRTbQ8pRUj9Yv2tbQoYAI1x6ENmKWQ_ahWMkkM,32706 +transformers/models/llava_next/processing_llava_next.py,sha256=skipesVMRszW3aCmyXymXShEtvDgJTXCnPIyp5WcqRc,10613 +transformers/models/llava_next_video/__init__.py,sha256=OGiUL7X9x0bzmsnZi0KA6Sl2ycalLQHkTgOpISYu3q8,1113 +transformers/models/llava_next_video/__pycache__/__init__.cpython-310.pyc,, +transformers/models/llava_next_video/__pycache__/configuration_llava_next_video.cpython-310.pyc,, +transformers/models/llava_next_video/__pycache__/modeling_llava_next_video.cpython-310.pyc,, +transformers/models/llava_next_video/__pycache__/modular_llava_next_video.cpython-310.pyc,, +transformers/models/llava_next_video/__pycache__/processing_llava_next_video.cpython-310.pyc,, +transformers/models/llava_next_video/__pycache__/video_processing_llava_next_video.cpython-310.pyc,, +transformers/models/llava_next_video/configuration_llava_next_video.py,sha256=y92eZcUlAaBmOaQAuoQWoYGDcagQpRFrhNUJ9hbd13U,8631 +transformers/models/llava_next_video/modeling_llava_next_video.py,sha256=_RRItpHVZKjjFhDi9La765TqHCv-m5ePSPVQgkAtPrU,43772 +transformers/models/llava_next_video/modular_llava_next_video.py,sha256=YAFomFizvbfdGuHVqdrEddiYi6CVywv4tMMu3dpaur4,35231 +transformers/models/llava_next_video/processing_llava_next_video.py,sha256=pG38uFnf-WGT20m60WhZEHY36Azyt_MKjD1FGQL2i4I,12147 +transformers/models/llava_next_video/video_processing_llava_next_video.py,sha256=M9zikrv4btULV6w01WgzWLoQsLFh1QZdOkr6xiFeLf8,1333 +transformers/models/llava_onevision/__init__.py,sha256=Eeg8yGcfdjCxwjSCg_zoXG48JG6gSYH8_aXBcOxQvnA,1218 +transformers/models/llava_onevision/__pycache__/__init__.cpython-310.pyc,, +transformers/models/llava_onevision/__pycache__/configuration_llava_onevision.cpython-310.pyc,, +transformers/models/llava_onevision/__pycache__/image_processing_llava_onevision.cpython-310.pyc,, +transformers/models/llava_onevision/__pycache__/image_processing_llava_onevision_fast.cpython-310.pyc,, +transformers/models/llava_onevision/__pycache__/modeling_llava_onevision.cpython-310.pyc,, +transformers/models/llava_onevision/__pycache__/modular_llava_onevision.cpython-310.pyc,, +transformers/models/llava_onevision/__pycache__/processing_llava_onevision.cpython-310.pyc,, +transformers/models/llava_onevision/__pycache__/video_processing_llava_onevision.cpython-310.pyc,, +transformers/models/llava_onevision/configuration_llava_onevision.py,sha256=uneVChPYmU_1EU_1o_ubIObuT8aSa8WKd3Ydci8y-UA,8426 +transformers/models/llava_onevision/image_processing_llava_onevision.py,sha256=Mjk5GXv3C7jvtCG18dslvQb_tN5FKH5EtlsJOP8SAo4,38360 +transformers/models/llava_onevision/image_processing_llava_onevision_fast.py,sha256=9sWnftxAVQoUtuowEZhW4ytaT2R-XYWzsGBCEjlm3nY,14137 +transformers/models/llava_onevision/modeling_llava_onevision.py,sha256=cU67o9siXlhQowYVrfSgYUKX6tzNqehBawrbcpN7DG8,42492 +transformers/models/llava_onevision/modular_llava_onevision.py,sha256=9Hw_G579CjmjV7-aDiOo6nyLVTt12eYEAQwKy9qwO4M,34142 +transformers/models/llava_onevision/processing_llava_onevision.py,sha256=pAZGfYrURXcwz9tLKckAKwi1-stoey8SxnY_ijZxJUg,14146 +transformers/models/llava_onevision/video_processing_llava_onevision.py,sha256=HESFKZLb3MKHPq_ONupz6cN4RZYGippChiPIMsSvD8c,1343 +transformers/models/longcat_flash/__init__.py,sha256=UhywfXc2iMxAuE8H--Mm6vxHLlKUp0FAAe0aq8QBxKA,1025 +transformers/models/longcat_flash/__pycache__/__init__.cpython-310.pyc,, +transformers/models/longcat_flash/__pycache__/configuration_longcat_flash.cpython-310.pyc,, +transformers/models/longcat_flash/__pycache__/modeling_longcat_flash.cpython-310.pyc,, +transformers/models/longcat_flash/__pycache__/modular_longcat_flash.cpython-310.pyc,, +transformers/models/longcat_flash/configuration_longcat_flash.py,sha256=MjcPOtOFT7F7EU0iZ10ap60Le8rPuZbORD3kCE5vHEQ,12111 +transformers/models/longcat_flash/modeling_longcat_flash.py,sha256=_hJ0O2HsXBngNBxEIqwe1eIw5G6j5pZriixkW8UzZ9M,32368 +transformers/models/longcat_flash/modular_longcat_flash.py,sha256=1NhUF2ayyJaKOlfuUm5viF5iqcjfTCUUCyayis0rCuc,18310 +transformers/models/longformer/__init__.py,sha256=qPm9rxvA-GeXV4gkzDqwu-SooVa3SBUvYI8C_SFgeYE,1088 +transformers/models/longformer/__pycache__/__init__.cpython-310.pyc,, +transformers/models/longformer/__pycache__/configuration_longformer.cpython-310.pyc,, +transformers/models/longformer/__pycache__/modeling_longformer.cpython-310.pyc,, +transformers/models/longformer/configuration_longformer.py,sha256=-bIvN1PQkWm5u_i6g-uy-GcDVoUyYcKZ2-TeNftxggM,6324 +transformers/models/longformer/modeling_longformer.py,sha256=vf31l_MtglKa9bjDF_rH8hcG-_C0_oL2CGZHdVl48F0,103166 +transformers/models/longt5/__init__.py,sha256=nmh4Vo8chv_I8xPFPFKu3Rfa_YbctUxl4ik5Ao-AaIM,993 +transformers/models/longt5/__pycache__/__init__.cpython-310.pyc,, +transformers/models/longt5/__pycache__/configuration_longt5.cpython-310.pyc,, +transformers/models/longt5/__pycache__/modeling_longt5.cpython-310.pyc,, +transformers/models/longt5/configuration_longt5.py,sha256=MDIqhoGthNw6VqFPPqDwD_nOtJd5iqc6H7JmjYLJdeM,7196 +transformers/models/longt5/modeling_longt5.py,sha256=O5eEwTYzLf03dmP_FBeh8GfmcPU7sulGpbCnQ6Aj9II,86059 +transformers/models/luke/__init__.py,sha256=YQL403sV6tk5t8sjvi-4hgvx1rvyThx45l7S4T4xpEE,1026 +transformers/models/luke/__pycache__/__init__.cpython-310.pyc,, +transformers/models/luke/__pycache__/configuration_luke.cpython-310.pyc,, +transformers/models/luke/__pycache__/modeling_luke.cpython-310.pyc,, +transformers/models/luke/__pycache__/tokenization_luke.cpython-310.pyc,, +transformers/models/luke/configuration_luke.py,sha256=oYdK8wUjRFvtd9JkEPVJ_4m433yyK83qYmDpFkmtA4o,6859 +transformers/models/luke/modeling_luke.py,sha256=mACTjSm0qF5wY7kg_qRr4M_PX88Mgy3QH55FUc4c_Po,95981 +transformers/models/luke/tokenization_luke.py,sha256=974FzW2AXiu5_1iWb82zLcAj8H6saV1lz8cpNa7NjI4,82055 +transformers/models/lw_detr/__init__.py,sha256=aR6j6aZ-ntKyVKN1HzWJHOPLZjeNK9iVKg-476Chk04,995 +transformers/models/lw_detr/__pycache__/__init__.cpython-310.pyc,, +transformers/models/lw_detr/__pycache__/configuration_lw_detr.cpython-310.pyc,, +transformers/models/lw_detr/__pycache__/modeling_lw_detr.cpython-310.pyc,, +transformers/models/lw_detr/__pycache__/modular_lw_detr.cpython-310.pyc,, +transformers/models/lw_detr/configuration_lw_detr.py,sha256=RCoN9P3oksMt2f19nffy9MdbNQ8C_ztu3P-VIW2wv0A,18965 +transformers/models/lw_detr/modeling_lw_detr.py,sha256=wMIHMKJQDJqULb1hbT3sUed6siDfsCoAjzNkQVmAw3k,75969 +transformers/models/lw_detr/modular_lw_detr.py,sha256=J0w9FBEfs3boYAq5sduytMc4iuzg3YWMFmjM_j5ZXZ8,72373 +transformers/models/lxmert/__init__.py,sha256=kt9QI783KwDwwUPx4BIY8AH-IHKydHuVJal6hRZpINU,1067 +transformers/models/lxmert/__pycache__/__init__.cpython-310.pyc,, +transformers/models/lxmert/__pycache__/configuration_lxmert.cpython-310.pyc,, +transformers/models/lxmert/__pycache__/modeling_lxmert.cpython-310.pyc,, +transformers/models/lxmert/configuration_lxmert.py,sha256=iI68lQ1Lu71i1IpKDkCosOjIQZW7HBmJ-CURuWuG7S4,9313 +transformers/models/lxmert/modeling_lxmert.py,sha256=tmOZaVkjpjyW9LOVEJMSfAK3wKKrdazeSNcyiQQD9eI,58743 +transformers/models/m2m_100/__init__.py,sha256=0uPov299rgQmMwwSyM_m0yGFejP5djgaUY37GkNGnC8,1035 +transformers/models/m2m_100/__pycache__/__init__.cpython-310.pyc,, +transformers/models/m2m_100/__pycache__/configuration_m2m_100.cpython-310.pyc,, +transformers/models/m2m_100/__pycache__/modeling_m2m_100.cpython-310.pyc,, +transformers/models/m2m_100/__pycache__/tokenization_m2m_100.cpython-310.pyc,, +transformers/models/m2m_100/configuration_m2m_100.py,sha256=R_5RIp87-hXhvBfJgenwebeCKq4J4qUMYgrUD3tr2EI,7131 +transformers/models/m2m_100/modeling_m2m_100.py,sha256=9ZyDw2O5mbr0xV8ibdjG4BLHFyj1cn7G0Vi3p32TxJ0,51505 +transformers/models/m2m_100/tokenization_m2m_100.py,sha256=II_GyUrqHFNEFzTylsmYDQ-aWskX7byIXtXvwnmrrOE,16373 +transformers/models/mamba/__init__.py,sha256=4oGJySQbwoALRGVWMEwXBm0A6fhKsr4Raly46a5g1G0,991 +transformers/models/mamba/__pycache__/__init__.cpython-310.pyc,, +transformers/models/mamba/__pycache__/configuration_mamba.cpython-310.pyc,, +transformers/models/mamba/__pycache__/modeling_mamba.cpython-310.pyc,, +transformers/models/mamba/configuration_mamba.py,sha256=pMkXzJQZ0lNRgk5NDdpFONis3ptm11RUUTKputgdn6Y,8150 +transformers/models/mamba/modeling_mamba.py,sha256=G9E3S57rbqJRAnU4eBwbmWYj1Bb8XDEWnxAdGjoOs-M,40587 +transformers/models/mamba2/__init__.py,sha256=Ui4j-I2cnPEEszkzRTLSUW42SE4Qg1YTuW6hGeaOFZg,993 +transformers/models/mamba2/__pycache__/__init__.cpython-310.pyc,, +transformers/models/mamba2/__pycache__/configuration_mamba2.cpython-310.pyc,, +transformers/models/mamba2/__pycache__/modeling_mamba2.cpython-310.pyc,, +transformers/models/mamba2/configuration_mamba2.py,sha256=gqDS-hNqOi7SkLmOf3RBBH0gTZqSpdTVfNag3-4KaVU,8184 +transformers/models/mamba2/modeling_mamba2.py,sha256=8nY6LmKYSllJjCTrSh2ktv-tWqKHHTdbP3KwnszJZn0,48169 +transformers/models/marian/__init__.py,sha256=IavSoQb-8nSlrq_0eDIkX4zD1tGNj4ybHyRKrDOTnMY,1032 +transformers/models/marian/__pycache__/__init__.cpython-310.pyc,, +transformers/models/marian/__pycache__/configuration_marian.cpython-310.pyc,, +transformers/models/marian/__pycache__/modeling_marian.cpython-310.pyc,, +transformers/models/marian/__pycache__/tokenization_marian.cpython-310.pyc,, +transformers/models/marian/configuration_marian.py,sha256=nlpnn8agTz7YaWahOXBZztcPI2WY6R21QPLy0Ps_d6I,7837 +transformers/models/marian/modeling_marian.py,sha256=iM3onjKu5uBCkxcAmccECfwMg6HG7HjZlzfc74f9ihM,61172 +transformers/models/marian/tokenization_marian.py,sha256=14YSQmg4xlvitWyRhFGVOGi1Fa3Q-ZP-u_TjkM6czL0,18086 +transformers/models/markuplm/__init__.py,sha256=-zg9rYmX3BVnq2mZPjDnW2bvZv2LIu6vm_y9grRTTRU,1083 +transformers/models/markuplm/__pycache__/__init__.cpython-310.pyc,, +transformers/models/markuplm/__pycache__/configuration_markuplm.cpython-310.pyc,, +transformers/models/markuplm/__pycache__/feature_extraction_markuplm.cpython-310.pyc,, +transformers/models/markuplm/__pycache__/modeling_markuplm.cpython-310.pyc,, +transformers/models/markuplm/__pycache__/processing_markuplm.cpython-310.pyc,, +transformers/models/markuplm/__pycache__/tokenization_markuplm.cpython-310.pyc,, +transformers/models/markuplm/configuration_markuplm.py,sha256=23UgTNtrtQrRSGyz2wP7XQpIixKNWZSSoYGACyIzYjY,7203 +transformers/models/markuplm/feature_extraction_markuplm.py,sha256=DTZiB6aiAsEW1sPj_w5qTtr76BSVCpd15wmZUXCuj9A,6428 +transformers/models/markuplm/modeling_markuplm.py,sha256=ppT37N3s43KdG59UlFdnjsRZCs1_WGCF9Qsfux_KGT8,39525 +transformers/models/markuplm/processing_markuplm.py,sha256=pTpnvCXls-BqlEL0KG0OuIhEB5M-KMwj7shprN8iY1k,5710 +transformers/models/markuplm/tokenization_markuplm.py,sha256=NCA_J-GDnJmNNiFkZ3VZxbFgyy23Uct9SiOwG9XImkw,48683 +transformers/models/mask2former/__init__.py,sha256=ceWZ-4gEaZxvgdhdvM-K18wZxuovtdS8vXkQIFNlfr4,1104 +transformers/models/mask2former/__pycache__/__init__.cpython-310.pyc,, +transformers/models/mask2former/__pycache__/configuration_mask2former.cpython-310.pyc,, +transformers/models/mask2former/__pycache__/image_processing_mask2former.cpython-310.pyc,, +transformers/models/mask2former/__pycache__/image_processing_mask2former_fast.cpython-310.pyc,, +transformers/models/mask2former/__pycache__/modeling_mask2former.cpython-310.pyc,, +transformers/models/mask2former/__pycache__/modular_mask2former.cpython-310.pyc,, +transformers/models/mask2former/configuration_mask2former.py,sha256=ubG20EaFTJFXS3bYxVA0uZ96G13PGUMdmBB7s24fDuw,9741 +transformers/models/mask2former/image_processing_mask2former.py,sha256=Go4prhR1CYi6MrhQZrkFBrrYh-QgszgYgIre3iBzi8E,57877 +transformers/models/mask2former/image_processing_mask2former_fast.py,sha256=KVuFTTF9qjyBRK712CDAN-htUPsSmiperKHunB6nYQk,32348 +transformers/models/mask2former/modeling_mask2former.py,sha256=v5tBivPCyBbYggNC6yRHHNsAf8Z-W5guoBoEg531HKo,117558 +transformers/models/mask2former/modular_mask2former.py,sha256=8CF1tF24x25XMhswD7Npm-zwICVCSiSJU72f5GRJmc0,15516 +transformers/models/maskformer/__init__.py,sha256=DWCF0SA7DGofmzu3y-j05x1NLeuKZHADvyyx4XfJwkw,1242 +transformers/models/maskformer/__pycache__/__init__.cpython-310.pyc,, +transformers/models/maskformer/__pycache__/configuration_maskformer.cpython-310.pyc,, +transformers/models/maskformer/__pycache__/configuration_maskformer_swin.cpython-310.pyc,, +transformers/models/maskformer/__pycache__/image_processing_maskformer.cpython-310.pyc,, +transformers/models/maskformer/__pycache__/image_processing_maskformer_fast.cpython-310.pyc,, +transformers/models/maskformer/__pycache__/modeling_maskformer.cpython-310.pyc,, +transformers/models/maskformer/__pycache__/modeling_maskformer_swin.cpython-310.pyc,, +transformers/models/maskformer/configuration_maskformer.py,sha256=ezTfgCaV42cN6btCb6G3cqnvUSJU4Q3uYg-IOtMarEY,7694 +transformers/models/maskformer/configuration_maskformer_swin.py,sha256=ZyJFX5136_kt1uxEFCtUNKPF7-mmJGFx2YeeR83xvJg,7093 +transformers/models/maskformer/image_processing_maskformer.py,sha256=mPTSecDFVUGh0LSsyplGhtBZ1Uer8xDUCF_SYW9GGlw,56442 +transformers/models/maskformer/image_processing_maskformer_fast.py,sha256=gEGcK_dJtcHOTK4mGBeV0zpu1Mv1K5Wmu9c8L9EC_Mc,31339 +transformers/models/maskformer/modeling_maskformer.py,sha256=SoKZdDyABU45fpCxvtqqE4gGo7KQOwADFcNPdsmo5G0,85299 +transformers/models/maskformer/modeling_maskformer_swin.py,sha256=YM5eA9qWqy8b8Xw9ZRinfjtR4dd76iBw07BB23T1zck,37582 +transformers/models/mbart/__init__.py,sha256=VYCZE-XKXmLlOTjcAToavJNZALlW0UNqkgdcdhLnm8c,1029 +transformers/models/mbart/__pycache__/__init__.cpython-310.pyc,, +transformers/models/mbart/__pycache__/configuration_mbart.cpython-310.pyc,, +transformers/models/mbart/__pycache__/modeling_mbart.cpython-310.pyc,, +transformers/models/mbart/__pycache__/tokenization_mbart.cpython-310.pyc,, +transformers/models/mbart/configuration_mbart.py,sha256=Cvn0pdHmrFAUA0MFug_-9m38gwlSm3b7VsyArkCbuIs,7741 +transformers/models/mbart/modeling_mbart.py,sha256=w_tH0ZC2G9mSQIe1DH7SAGFINvC1bM4LgKYmdcW1nGY,70665 +transformers/models/mbart/tokenization_mbart.py,sha256=iChlZW6tL561ENOD_oTXF97aUcCk0kI0Qfmm9QA8njE,8473 +transformers/models/mbart50/__init__.py,sha256=ZxOzDc6AP0x0jp3EgGeQZx1xOApVeWbuQan7aqj-Xeo,958 +transformers/models/mbart50/__pycache__/__init__.cpython-310.pyc,, +transformers/models/mbart50/__pycache__/tokenization_mbart50.cpython-310.pyc,, +transformers/models/mbart50/tokenization_mbart50.py,sha256=SRLYweqPO2HkV9nnGOo3MnpLHDVfKNmY-Wy2X89DV9g,14366 +transformers/models/megatron_bert/__init__.py,sha256=u1UIYjQlrfHcy81i2FzehRDJpt6KNfNJ4AePQYKgwOU,1007 +transformers/models/megatron_bert/__pycache__/__init__.cpython-310.pyc,, +transformers/models/megatron_bert/__pycache__/configuration_megatron_bert.cpython-310.pyc,, +transformers/models/megatron_bert/__pycache__/modeling_megatron_bert.cpython-310.pyc,, +transformers/models/megatron_bert/configuration_megatron_bert.py,sha256=TeK8PfB3SlL3CplTlCjH5akgw5K--063hKvzRkrDltA,6129 +transformers/models/megatron_bert/modeling_megatron_bert.py,sha256=wqE2pDqfPnVHdd9A39yPXeqpKr7oUlsu6XpBR1B_8YI,61412 +transformers/models/megatron_gpt2/__init__.py,sha256=47DEQpj8HBSa-_TImW-5JCeuQeRkm5NMpJWZG3hSuFU,0 +transformers/models/megatron_gpt2/__pycache__/__init__.cpython-310.pyc,, +transformers/models/megatron_gpt2/__pycache__/checkpoint_reshaping_and_interoperability.cpython-310.pyc,, +transformers/models/megatron_gpt2/checkpoint_reshaping_and_interoperability.py,sha256=3Oe0z75_0SQSM4OR-hRtH_w24LmhSV9AgsyzwKA2R9Y,37650 +transformers/models/metaclip_2/__init__.py,sha256=S5n45gZa_DwDJ3PtBbKzcjqDd6uOY4sbsSXR227oFZI,1001 +transformers/models/metaclip_2/__pycache__/__init__.cpython-310.pyc,, +transformers/models/metaclip_2/__pycache__/configuration_metaclip_2.cpython-310.pyc,, +transformers/models/metaclip_2/__pycache__/modeling_metaclip_2.cpython-310.pyc,, +transformers/models/metaclip_2/__pycache__/modular_metaclip_2.cpython-310.pyc,, +transformers/models/metaclip_2/configuration_metaclip_2.py,sha256=KOrkF5zw2qjrebkSX1uKtpb2EIoFUO15AWhPz_HIQHg,18052 +transformers/models/metaclip_2/modeling_metaclip_2.py,sha256=qs0wERh8BjaCN4MjA8ayNrSP45VgJctzJ0nFvVoFUZg,52206 +transformers/models/metaclip_2/modular_metaclip_2.py,sha256=acFCJjkIu0sZcxzFbeCykP22jo2wwuVoOvaozL_wawU,33736 +transformers/models/mgp_str/__init__.py,sha256=Qb3mXPCrWbQ1ksMRYMeXorrva97OOFNr1zoy4YQg-9k,1073 +transformers/models/mgp_str/__pycache__/__init__.cpython-310.pyc,, +transformers/models/mgp_str/__pycache__/configuration_mgp_str.cpython-310.pyc,, +transformers/models/mgp_str/__pycache__/modeling_mgp_str.cpython-310.pyc,, +transformers/models/mgp_str/__pycache__/processing_mgp_str.cpython-310.pyc,, +transformers/models/mgp_str/__pycache__/tokenization_mgp_str.cpython-310.pyc,, +transformers/models/mgp_str/configuration_mgp_str.py,sha256=lK-qmv8dNVqpUB64FjwXr4bRFsXPx6UL7_IsB-yZWew,5795 +transformers/models/mgp_str/modeling_mgp_str.py,sha256=k_s_OvLxvoNQ9tQpqSNz92Xcw5SLAbc1cJiq1KN4FHg,18435 +transformers/models/mgp_str/processing_mgp_str.py,sha256=UDIB0OiQH9v7waJ-0khtCBO6Hv0vCj8bYMr0VPKzEaE,7804 +transformers/models/mgp_str/tokenization_mgp_str.py,sha256=XrqjbDcTci9sZ-d-CXHlzzhwyw7h0lAnD6GRouCNYrs,3791 +transformers/models/mimi/__init__.py,sha256=VXRZ-D8-AyOYcmRGvSxhjwTYQcSNXcCXi5ubks6Qxhk,989 +transformers/models/mimi/__pycache__/__init__.cpython-310.pyc,, +transformers/models/mimi/__pycache__/configuration_mimi.cpython-310.pyc,, +transformers/models/mimi/__pycache__/modeling_mimi.cpython-310.pyc,, +transformers/models/mimi/configuration_mimi.py,sha256=1Vqbg_W1dE-oqvpiqi5a0AePd7Eue3znxfoTDsk1v6g,14582 +transformers/models/mimi/modeling_mimi.py,sha256=KifchDhFrZNK0Rx5fDeRCGf7ON-520sDQ7iEA8mnPAc,80323 +transformers/models/minimax/__init__.py,sha256=hP-D2E-RR4ySxC0IkUuB8AatsJj3vOX1-VbWQ01WwAM,1013 +transformers/models/minimax/__pycache__/__init__.cpython-310.pyc,, +transformers/models/minimax/__pycache__/configuration_minimax.cpython-310.pyc,, +transformers/models/minimax/__pycache__/modeling_minimax.cpython-310.pyc,, +transformers/models/minimax/__pycache__/modular_minimax.cpython-310.pyc,, +transformers/models/minimax/configuration_minimax.py,sha256=Dhe1hfSEyLEtvVWBUC9yZ4QmjSKgxhKPjwcgvc1-m_k,12564 +transformers/models/minimax/modeling_minimax.py,sha256=v43mJABCmF-Q1a7nbpVKHeyXRMC7saJZxJHEMSXq_Qs,41368 +transformers/models/minimax/modular_minimax.py,sha256=jVBEVCLhE9zOO1IJk1W8usgQuJorRZGnStC8RPQ1LnE,29593 +transformers/models/minimax_m2/__init__.py,sha256=DtCF0nGskHZe44Z1-UfHth74oV7lXM52VPncoKsSzXQ,1002 +transformers/models/minimax_m2/__pycache__/__init__.cpython-310.pyc,, +transformers/models/minimax_m2/__pycache__/configuration_minimax_m2.cpython-310.pyc,, +transformers/models/minimax_m2/__pycache__/modeling_minimax_m2.cpython-310.pyc,, +transformers/models/minimax_m2/__pycache__/modular_minimax_m2.cpython-310.pyc,, +transformers/models/minimax_m2/configuration_minimax_m2.py,sha256=HtcHUTqMBfz9ukdBCv-2Z8oZZSq-HaGjJgKIT9F7efE,10061 +transformers/models/minimax_m2/modeling_minimax_m2.py,sha256=vWbfNLaqBIXvqEVHHC5L8KW2LLCt5VNvsKFoNes0snc,31539 +transformers/models/minimax_m2/modular_minimax_m2.py,sha256=dosUkibrjOTxyjcvnSriLFdQcNTDqfNDk_gp6HdMV7o,15900 +transformers/models/ministral/__init__.py,sha256=618E2UYWKhHRaJQnG5YToNFqqiEPQBnYNlAVyZq889c,1019 +transformers/models/ministral/__pycache__/__init__.cpython-310.pyc,, +transformers/models/ministral/__pycache__/configuration_ministral.cpython-310.pyc,, +transformers/models/ministral/__pycache__/modeling_ministral.cpython-310.pyc,, +transformers/models/ministral/__pycache__/modular_ministral.cpython-310.pyc,, +transformers/models/ministral/configuration_ministral.py,sha256=KsycdJ14urppF3332XP31z9HNKD06ie5BE16N1GV1Yw,8800 +transformers/models/ministral/modeling_ministral.py,sha256=0ldKa6475pVShw1MC9OeXgDC6raBFphu8d1RbYoKfv8,22638 +transformers/models/ministral/modular_ministral.py,sha256=hFcK3I7Z-vAYultQePQNwchvx4pOerJ1bz0TeWtntT8,12388 +transformers/models/ministral3/__init__.py,sha256=5_FEbQFnuUpKN4SRGHPrlEwB_zYU28vzWuUcwTm8Q8E,1021 +transformers/models/ministral3/__pycache__/__init__.cpython-310.pyc,, +transformers/models/ministral3/__pycache__/configuration_ministral3.cpython-310.pyc,, +transformers/models/ministral3/__pycache__/modeling_ministral3.cpython-310.pyc,, +transformers/models/ministral3/__pycache__/modular_ministral3.cpython-310.pyc,, +transformers/models/ministral3/configuration_ministral3.py,sha256=L55fFLhieefvep90AAFLUUmHVRCRhWjgeHJ_bYkYa7Q,9773 +transformers/models/ministral3/modeling_ministral3.py,sha256=pT46DzUebqDrZr0QlwNN-sbH92-_rA7ZgSb7rVCnDSY,22504 +transformers/models/ministral3/modular_ministral3.py,sha256=wcyQ8OjrB6zqkvR7cfvcOApAZVIfFvyknKH3pkIjYLg,4039 +transformers/models/mistral/__init__.py,sha256=uMtejpzqHBbx1-TTTyda0f9lIZlqvdvrV45C-MFTyt4,1015 +transformers/models/mistral/__pycache__/__init__.cpython-310.pyc,, +transformers/models/mistral/__pycache__/configuration_mistral.cpython-310.pyc,, +transformers/models/mistral/__pycache__/modeling_mistral.cpython-310.pyc,, +transformers/models/mistral/__pycache__/modular_mistral.cpython-310.pyc,, +transformers/models/mistral/configuration_mistral.py,sha256=PUz4HiTlMzg2hMCISfWoWsptfywn1lL6pMSo8aZtZd4,8628 +transformers/models/mistral/modeling_mistral.py,sha256=0QfaXpGTgFuIblGNXQWrvy3VTtpt9fNlauFA_gihQh8,21827 +transformers/models/mistral/modular_mistral.py,sha256=ydfRSju1qiyM3MWSEXMJdcBF5Hw-0ZpDMAnNdkopZ-8,7532 +transformers/models/mistral3/__init__.py,sha256=ccR4AQqjFkPl8JVYyVmVvbVm618FlOw4cpwT7N-8ZD4,1036 +transformers/models/mistral3/__pycache__/__init__.cpython-310.pyc,, +transformers/models/mistral3/__pycache__/configuration_mistral3.cpython-310.pyc,, +transformers/models/mistral3/__pycache__/modeling_mistral3.cpython-310.pyc,, +transformers/models/mistral3/__pycache__/modular_mistral3.cpython-310.pyc,, +transformers/models/mistral3/configuration_mistral3.py,sha256=BzpWIAwHUsjCk_ADFew13jFrQJhC5cBl88wbXLewFwI,5922 +transformers/models/mistral3/modeling_mistral3.py,sha256=CNNeYI7FeGo8Yo14hKJJ-DCztxHm0CSsaWSpNDUakKk,22745 +transformers/models/mistral3/modular_mistral3.py,sha256=sfRauVs6a5nMggvJM22bwa3RyO9Jj607t1C6z9ojWQw,13997 +transformers/models/mixtral/__init__.py,sha256=_i66uHDx5A0-UBwgR2nwibxSf0ZePqpTa_Qsm0Cg_Bs,1015 +transformers/models/mixtral/__pycache__/__init__.cpython-310.pyc,, +transformers/models/mixtral/__pycache__/configuration_mixtral.cpython-310.pyc,, +transformers/models/mixtral/__pycache__/modeling_mixtral.cpython-310.pyc,, +transformers/models/mixtral/__pycache__/modular_mixtral.cpython-310.pyc,, +transformers/models/mixtral/configuration_mixtral.py,sha256=tKePIPjNAb1Y3bhsgW6N7BLPnHXQxfr2YPreFvO30CE,9685 +transformers/models/mixtral/modeling_mixtral.py,sha256=fZVwDxepVRdyEKkjtFEmOUax7PRcGek0M6CDKIW_yCo,31276 +transformers/models/mixtral/modular_mixtral.py,sha256=EaC3a1bEkoozcVxUBZUfSwAqCm5BtLzrPnamhUHQOko,18704 +transformers/models/mlcd/__init__.py,sha256=hLiLB1E0jT7sI3s8TraLb_Z1WOpwS69zac5kyHNfx4E,989 +transformers/models/mlcd/__pycache__/__init__.cpython-310.pyc,, +transformers/models/mlcd/__pycache__/configuration_mlcd.cpython-310.pyc,, +transformers/models/mlcd/__pycache__/modeling_mlcd.cpython-310.pyc,, +transformers/models/mlcd/__pycache__/modular_mlcd.cpython-310.pyc,, +transformers/models/mlcd/configuration_mlcd.py,sha256=C-r5Vg-6jvxEWXZjIedSUPp-TqgZ85R1xnvdm4a-UMQ,5789 +transformers/models/mlcd/modeling_mlcd.py,sha256=HiL_UmeXj-SF9_06c16mEsqqf6OWqL1ZOwI10ohTdRw,24681 +transformers/models/mlcd/modular_mlcd.py,sha256=X9ObiAN2E8JnoQeeR69I0BNuYLJBEAN_EsIIVq2owOc,20295 +transformers/models/mllama/__init__.py,sha256=EzCpjuAv2Ke2xlpINWvTPIZLnYxA8D-2mvlGTZu6Zj4,1121 +transformers/models/mllama/__pycache__/__init__.cpython-310.pyc,, +transformers/models/mllama/__pycache__/configuration_mllama.cpython-310.pyc,, +transformers/models/mllama/__pycache__/image_processing_mllama.cpython-310.pyc,, +transformers/models/mllama/__pycache__/image_processing_mllama_fast.cpython-310.pyc,, +transformers/models/mllama/__pycache__/modeling_mllama.cpython-310.pyc,, +transformers/models/mllama/__pycache__/processing_mllama.cpython-310.pyc,, +transformers/models/mllama/configuration_mllama.py,sha256=Iq1ySgpfhKWUjrVKYrEvbXBLVWWTIFyyidx4CZAq5go,15234 +transformers/models/mllama/image_processing_mllama.py,sha256=1td5E5uFG5UcV7-TQQCYBng0L0ENf8VJL5A1Q5jHCkM,37265 +transformers/models/mllama/image_processing_mllama_fast.py,sha256=c8vchu2AZlsXe56SsH1_iF2zaKXFl98QdvJglaS3RMM,15680 +transformers/models/mllama/modeling_mllama.py,sha256=ez1p0PQTdo7fA-of_M8dt3d-yFJK1Lq4eD57_3azCiU,73921 +transformers/models/mllama/processing_mllama.py,sha256=ge5kwpV3gs6cgPR2PnIsnUc_RXfxDJ1gvopR7471TmQ,14026 +transformers/models/mluke/__init__.py,sha256=e_3cNftWOmhNXk-zsA1-2DOBT9L56SHr-6qev0xI7Ws,956 +transformers/models/mluke/__pycache__/__init__.cpython-310.pyc,, +transformers/models/mluke/__pycache__/tokenization_mluke.cpython-310.pyc,, +transformers/models/mluke/tokenization_mluke.py,sha256=FH4j2tLjY6IalXMKHFbK_KW6Eu8kCQw0DI6O9vSczfc,88069 +transformers/models/mm_grounding_dino/__init__.py,sha256=mk2hUY_rZw6JSjfkqSL4hVYJKxh5ViM3TZfib-09kpc,1015 +transformers/models/mm_grounding_dino/__pycache__/__init__.cpython-310.pyc,, +transformers/models/mm_grounding_dino/__pycache__/configuration_mm_grounding_dino.cpython-310.pyc,, +transformers/models/mm_grounding_dino/__pycache__/modeling_mm_grounding_dino.cpython-310.pyc,, +transformers/models/mm_grounding_dino/__pycache__/modular_mm_grounding_dino.cpython-310.pyc,, +transformers/models/mm_grounding_dino/configuration_mm_grounding_dino.py,sha256=j2WCGpfPFxSu7D4LRNHofxYom_h1jwX6hsZJCqT-aII,12831 +transformers/models/mm_grounding_dino/modeling_mm_grounding_dino.py,sha256=_pArUkkFm9qcDm_Si0oz9T0BSBLjiRL5ycJdC-JuGas,128415 +transformers/models/mm_grounding_dino/modular_mm_grounding_dino.py,sha256=iOFAji-j882ABK3ENitPLBS3lP2bmsbjuugudKZK4GQ,17654 +transformers/models/mobilebert/__init__.py,sha256=Ahrfu5ZVpOcRpNP81dbzqZO9mJAz-gajqgpAZW5xj1Y,1087 +transformers/models/mobilebert/__pycache__/__init__.cpython-310.pyc,, +transformers/models/mobilebert/__pycache__/configuration_mobilebert.cpython-310.pyc,, +transformers/models/mobilebert/__pycache__/modeling_mobilebert.cpython-310.pyc,, +transformers/models/mobilebert/__pycache__/tokenization_mobilebert.cpython-310.pyc,, +transformers/models/mobilebert/configuration_mobilebert.py,sha256=ZYrVeiWjvn7qnC2RBWRLkcAgtGkmDA4wsn_bsOotb_s,7555 +transformers/models/mobilebert/modeling_mobilebert.py,sha256=OYGURY2LYKs5D7UruLgKYbkqLxLE1pqnLZqH-H68nSA,50885 +transformers/models/mobilebert/tokenization_mobilebert.py,sha256=7vAsL3wIML89C7QOqQpHA0YYCBFBvcNY4wBLnGPRJQc,1002 +transformers/models/mobilenet_v1/__init__.py,sha256=kS0kf8Q0rDhNcqIJM6iI6iVufztYwEl-TsOzVQZwn-Y,1159 +transformers/models/mobilenet_v1/__pycache__/__init__.cpython-310.pyc,, +transformers/models/mobilenet_v1/__pycache__/configuration_mobilenet_v1.cpython-310.pyc,, +transformers/models/mobilenet_v1/__pycache__/image_processing_mobilenet_v1.cpython-310.pyc,, +transformers/models/mobilenet_v1/__pycache__/image_processing_mobilenet_v1_fast.cpython-310.pyc,, +transformers/models/mobilenet_v1/__pycache__/modeling_mobilenet_v1.cpython-310.pyc,, +transformers/models/mobilenet_v1/configuration_mobilenet_v1.py,sha256=B0prIMcZtAQicuIzM9FN6mffSi1NhTEgChUa1Se-fKQ,4157 +transformers/models/mobilenet_v1/image_processing_mobilenet_v1.py,sha256=aJnK1o9P74dVZ2wXe0l1Ay05yqlwLiP8TKdujPBCVvY,14985 +transformers/models/mobilenet_v1/image_processing_mobilenet_v1_fast.py,sha256=aG4adaNucFZ_gzzgNWWL9XxpHwaOrcTJw3OSv9vC6pY,1315 +transformers/models/mobilenet_v1/modeling_mobilenet_v1.py,sha256=OGiA2Of7CaTz9V3DOG9cgYSJ74yJUrphipKz14qz0G8,10313 +transformers/models/mobilenet_v2/__init__.py,sha256=PGEnF5QRb3bZg_Iux0DuD7VPysu8nA0WxJEd6YOXtmw,1159 +transformers/models/mobilenet_v2/__pycache__/__init__.cpython-310.pyc,, +transformers/models/mobilenet_v2/__pycache__/configuration_mobilenet_v2.cpython-310.pyc,, +transformers/models/mobilenet_v2/__pycache__/image_processing_mobilenet_v2.cpython-310.pyc,, +transformers/models/mobilenet_v2/__pycache__/image_processing_mobilenet_v2_fast.cpython-310.pyc,, +transformers/models/mobilenet_v2/__pycache__/modeling_mobilenet_v2.cpython-310.pyc,, +transformers/models/mobilenet_v2/configuration_mobilenet_v2.py,sha256=VROByGcEfOoNLwGS_3ATymE3TtgYwEGjqLEVrTvbkk0,6053 +transformers/models/mobilenet_v2/image_processing_mobilenet_v2.py,sha256=T8C14YlEUXMQzAguLRM7gApC5W71zb_ArhvGD4hLRJE,24693 +transformers/models/mobilenet_v2/image_processing_mobilenet_v2_fast.py,sha256=-c8uSkHCOBJcc485nWu_f3asCF2O_QGnxZARntxLk3M,9017 +transformers/models/mobilenet_v2/modeling_mobilenet_v2.py,sha256=Q0GMxi2qNwXK55clxqL-YWntI6Ota21Iwm5YThQF-6I,21187 +transformers/models/mobilevit/__init__.py,sha256=1xy-4YP_-uEBx4eL8jVEjgN9mMwCT2Uj29YbovBBx50,1144 +transformers/models/mobilevit/__pycache__/__init__.cpython-310.pyc,, +transformers/models/mobilevit/__pycache__/configuration_mobilevit.cpython-310.pyc,, +transformers/models/mobilevit/__pycache__/image_processing_mobilevit.cpython-310.pyc,, +transformers/models/mobilevit/__pycache__/image_processing_mobilevit_fast.cpython-310.pyc,, +transformers/models/mobilevit/__pycache__/modeling_mobilevit.cpython-310.pyc,, +transformers/models/mobilevit/configuration_mobilevit.py,sha256=_CXQ-onVFRw0txhjqQdEqGV74eV8pw-X9KPkul6nn34,6774 +transformers/models/mobilevit/image_processing_mobilevit.py,sha256=HFnjkwWzMGR7oz0Tn-ww26tyuB45TJ8VSOrdqz7hfBQ,23639 +transformers/models/mobilevit/image_processing_mobilevit_fast.py,sha256=tEUTcFVXmk7H3TvvgU016LjZjyk1wqxWBg4RDcNVv1w,9054 +transformers/models/mobilevit/modeling_mobilevit.py,sha256=fxkXrsHEcsElMzLrx46F6glJ8sBc0jHxLWh0wDVPWfI,35146 +transformers/models/mobilevitv2/__init__.py,sha256=pAGk_9X22yOYvlcwbqTc4nm6fL4rPhAhDpdBguna5Q0,1003 +transformers/models/mobilevitv2/__pycache__/__init__.cpython-310.pyc,, +transformers/models/mobilevitv2/__pycache__/configuration_mobilevitv2.cpython-310.pyc,, +transformers/models/mobilevitv2/__pycache__/modeling_mobilevitv2.cpython-310.pyc,, +transformers/models/mobilevitv2/configuration_mobilevitv2.py,sha256=s1XWXLRjUTjTrZs2DVJr4_JG0LuQyla45BPyh-4kZU0,6333 +transformers/models/mobilevitv2/modeling_mobilevitv2.py,sha256=XLbn_lYl5fyvOz9e8QqUtIXr2hRYIT7c0D4QQZ_Wa14,33939 +transformers/models/modernbert/__init__.py,sha256=BEQFRFfcKvUlphA1ibW3s34Vkbm-MUuyqzaLbrIFiAA,1006 +transformers/models/modernbert/__pycache__/__init__.cpython-310.pyc,, +transformers/models/modernbert/__pycache__/configuration_modernbert.cpython-310.pyc,, +transformers/models/modernbert/__pycache__/modeling_modernbert.cpython-310.pyc,, +transformers/models/modernbert/__pycache__/modular_modernbert.cpython-310.pyc,, +transformers/models/modernbert/configuration_modernbert.py,sha256=fjc5kwRlzlGdl1qotrWat9Qe8mJLauXCL1xGryRDTZY,14840 +transformers/models/modernbert/modeling_modernbert.py,sha256=1lfnaKtBnLQQHTVk00bP6VtpFJ3UXh0vPgsvsTjGcAs,36771 +transformers/models/modernbert/modular_modernbert.py,sha256=_h9GEmOC0Hjv3x-9ShXJvYGalYGfwEHB88PXiuVlJ9s,44819 +transformers/models/modernbert_decoder/__init__.py,sha256=RjLebVKPcGgNEORY5xypTPd8oYWcnFmbGm3hBqQX-HE,1022 +transformers/models/modernbert_decoder/__pycache__/__init__.cpython-310.pyc,, +transformers/models/modernbert_decoder/__pycache__/configuration_modernbert_decoder.cpython-310.pyc,, +transformers/models/modernbert_decoder/__pycache__/modeling_modernbert_decoder.cpython-310.pyc,, +transformers/models/modernbert_decoder/__pycache__/modular_modernbert_decoder.cpython-310.pyc,, +transformers/models/modernbert_decoder/configuration_modernbert_decoder.py,sha256=SQ29i0PmQ5Ua7K9KUtWT8rgfxSf4bCXqseCRzhYwtQE,13003 +transformers/models/modernbert_decoder/modeling_modernbert_decoder.py,sha256=8PFIZJmKCmFLuD5CGaM37JX8IedDo5iBjWunqotxNxQ,34412 +transformers/models/modernbert_decoder/modular_modernbert_decoder.py,sha256=NdMkllRDmeloh_wh_UdLbbUmtlbZlsPVNIhWCW5xDsI,36900 +transformers/models/modernvbert/__init__.py,sha256=UoCdsSmgNKgJN49IMECdDqYXtUMpThFGSQE5UTvzCW4,1191 +transformers/models/modernvbert/__pycache__/__init__.cpython-310.pyc,, +transformers/models/modernvbert/__pycache__/configuration_modernvbert.cpython-310.pyc,, +transformers/models/modernvbert/__pycache__/modeling_modernvbert.cpython-310.pyc,, +transformers/models/modernvbert/__pycache__/modular_modernvbert.cpython-310.pyc,, +transformers/models/modernvbert/configuration_modernvbert.py,sha256=RzaFnn1nBb5eY52nX6rw0hZKvWLsGURYhnfYlbzNfbc,5602 +transformers/models/modernvbert/modeling_modernvbert.py,sha256=ud_Ahg06HytJiZwu_ZznLgJpTOS1ogsJVY-IOJP79vM,33508 +transformers/models/modernvbert/modular_modernvbert.py,sha256=U3CRweKwnm26KzW9sBnIds1GZFtYVQI430G_cbC_5oA,30211 +transformers/models/moonshine/__init__.py,sha256=eBgvc9LtoDnB6HnNvrObDWL3h_L4Sgn5-D-hepNfAmI,999 +transformers/models/moonshine/__pycache__/__init__.cpython-310.pyc,, +transformers/models/moonshine/__pycache__/configuration_moonshine.cpython-310.pyc,, +transformers/models/moonshine/__pycache__/modeling_moonshine.cpython-310.pyc,, +transformers/models/moonshine/__pycache__/modular_moonshine.cpython-310.pyc,, +transformers/models/moonshine/configuration_moonshine.py,sha256=1273Kk0DEFej0T5F_xDUsbRh7OyvOehom7c_qNNS7K4,11159 +transformers/models/moonshine/modeling_moonshine.py,sha256=9YbsjeHJiiur7AcAHdrqrLYWrKefUXUGpWDPps4uhMA,42484 +transformers/models/moonshine/modular_moonshine.py,sha256=fAJlfOA9Jv0520FkqCqam6F7-jYAzkXcCIpN_56kvGw,40496 +transformers/models/moonshine_streaming/__init__.py,sha256=9S0QRymrUyt5h-mdWY9w45E_kuoxd_mlBZuX8pLv65s,1020 +transformers/models/moonshine_streaming/__pycache__/__init__.cpython-310.pyc,, +transformers/models/moonshine_streaming/__pycache__/configuration_moonshine_streaming.cpython-310.pyc,, +transformers/models/moonshine_streaming/__pycache__/modeling_moonshine_streaming.cpython-310.pyc,, +transformers/models/moonshine_streaming/__pycache__/modular_moonshine_streaming.cpython-310.pyc,, +transformers/models/moonshine_streaming/__pycache__/processing_moonshine_streaming.cpython-310.pyc,, +transformers/models/moonshine_streaming/configuration_moonshine_streaming.py,sha256=MccVb8-thhtL2qumMCHrN0WSLyXSE5fOaxWLhtT1xr8,12782 +transformers/models/moonshine_streaming/modeling_moonshine_streaming.py,sha256=V-RZpkYLWA2ojE6DEYkqlCo2bOtVUgkEMIbIaLOhDVs,50065 +transformers/models/moonshine_streaming/modular_moonshine_streaming.py,sha256=atuDOVsflrOaNKwnTpTI7G6OlU3WrjuZ-sDInQYm-BA,16701 +transformers/models/moonshine_streaming/processing_moonshine_streaming.py,sha256=GcoGNJunzBg8SRe4B80IliE1SzCzKwLZDfL-v1VYt1Y,5173 +transformers/models/moshi/__init__.py,sha256=uW4oqTKZdbmURZaC_xwwHXnYEMyLJrMEJAlfbUzSWO8,991 +transformers/models/moshi/__pycache__/__init__.cpython-310.pyc,, +transformers/models/moshi/__pycache__/configuration_moshi.cpython-310.pyc,, +transformers/models/moshi/__pycache__/modeling_moshi.cpython-310.pyc,, +transformers/models/moshi/configuration_moshi.py,sha256=nZqUHV6zIwSyahqOIwAuxeDyrPhm_TRoyJiJdH-XT28,17613 +transformers/models/moshi/modeling_moshi.py,sha256=F1eS6hYNIFBZ2VZxbOKysnDwbwufrJgCxWUNCFoYD-M,104389 +transformers/models/mpnet/__init__.py,sha256=Lmtzs8K18d_lydT3fpJIAjwD0nBAZnNa6NdiNdqvEJg,1029 +transformers/models/mpnet/__pycache__/__init__.cpython-310.pyc,, +transformers/models/mpnet/__pycache__/configuration_mpnet.cpython-310.pyc,, +transformers/models/mpnet/__pycache__/modeling_mpnet.cpython-310.pyc,, +transformers/models/mpnet/__pycache__/tokenization_mpnet.cpython-310.pyc,, +transformers/models/mpnet/configuration_mpnet.py,sha256=FmE_J9QW4ZhCk6JJ3sxnzeZQ65eNiit3gmW6u9wod_4,5401 +transformers/models/mpnet/modeling_mpnet.py,sha256=m8MeUEqURcb0jUSz-ejBgz007lcD5pXNbgh6OPPDxLI,35067 +transformers/models/mpnet/tokenization_mpnet.py,sha256=5es3kknt0_UvkK2nxAX6v5cEpZ_orG_vHESkQHHdTnM,8732 +transformers/models/mpt/__init__.py,sha256=DAIIAY0kPL-bXMkPUvxmP97HCXPi-SoM3NLnlJJYarg,987 +transformers/models/mpt/__pycache__/__init__.cpython-310.pyc,, +transformers/models/mpt/__pycache__/configuration_mpt.cpython-310.pyc,, +transformers/models/mpt/__pycache__/modeling_mpt.cpython-310.pyc,, +transformers/models/mpt/configuration_mpt.py,sha256=dmVDhAzjuMEl6sej8FOHRGvFCf02NMVynHbSJYKIw2A,10859 +transformers/models/mpt/modeling_mpt.py,sha256=dVG_Oluzke74oxkQTnp3Z_lnyPZjrAZbMDmgn9x4oZo,32693 +transformers/models/mra/__init__.py,sha256=51mnm4DFq6aWxOsmaaVZDL28QozNauXyTtbEihDxUQU,987 +transformers/models/mra/__pycache__/__init__.cpython-310.pyc,, +transformers/models/mra/__pycache__/configuration_mra.cpython-310.pyc,, +transformers/models/mra/__pycache__/modeling_mra.cpython-310.pyc,, +transformers/models/mra/configuration_mra.py,sha256=ljyaDdfyGWU2Ok2F_xHCceJB47l7ygWyM8xk8NTZOAk,6446 +transformers/models/mra/modeling_mra.py,sha256=G-W51_y1X4OUQIdpm9L9QIcgh7yYseSB4RmqqI5YHD4,53708 +transformers/models/mt5/__init__.py,sha256=BTuFEuI7Ojp3tXOaLCepiUPbxYxotr4_ToZ1eXvITyA,1023 +transformers/models/mt5/__pycache__/__init__.cpython-310.pyc,, +transformers/models/mt5/__pycache__/configuration_mt5.cpython-310.pyc,, +transformers/models/mt5/__pycache__/modeling_mt5.cpython-310.pyc,, +transformers/models/mt5/configuration_mt5.py,sha256=gT8Li-d74hIX_fi6pEjEWeIqkAbJ590f-f0noUjnU3s,6877 +transformers/models/mt5/modeling_mt5.py,sha256=AYT6-rzZ4B_C6Q4QI-fqb8lzdJ33d8uR1Btb_DemGS4,77287 +transformers/models/musicgen/__init__.py,sha256=iwtW9pg6iDe5D2dWVC4IRU8QbNmRK5kMqPCM8fsUSgo,1036 +transformers/models/musicgen/__pycache__/__init__.cpython-310.pyc,, +transformers/models/musicgen/__pycache__/configuration_musicgen.cpython-310.pyc,, +transformers/models/musicgen/__pycache__/modeling_musicgen.cpython-310.pyc,, +transformers/models/musicgen/__pycache__/processing_musicgen.cpython-310.pyc,, +transformers/models/musicgen/configuration_musicgen.py,sha256=jWA0xL2xciStqvARBsiFpClDNsJMI6gDiyb3ezW38bQ,10350 +transformers/models/musicgen/modeling_musicgen.py,sha256=I9P15KyJjS7-dQWi6fbzCOQbWxRXSatpTVevKwDS2Ys,109583 +transformers/models/musicgen/processing_musicgen.py,sha256=Tj7AG78Ai04tF0izuDwMS8iY1lMnz_lSsa1BlhwVuJk,3360 +transformers/models/musicgen_melody/__init__.py,sha256=WVEsVs7g0XlpO_yd1X0X4QnMjhG0h_n6T41FpdJcnS8,1011 +transformers/models/musicgen_melody/__pycache__/__init__.cpython-310.pyc,, +transformers/models/musicgen_melody/__pycache__/configuration_musicgen_melody.cpython-310.pyc,, +transformers/models/musicgen_melody/__pycache__/feature_extraction_musicgen_melody.cpython-310.pyc,, +transformers/models/musicgen_melody/__pycache__/modeling_musicgen_melody.cpython-310.pyc,, +transformers/models/musicgen_melody/__pycache__/processing_musicgen_melody.cpython-310.pyc,, +transformers/models/musicgen_melody/configuration_musicgen_melody.py,sha256=fU66zIveWodHE0fUsZeV1BYz-PWFg6cBi7Bl1NC1bGM,11657 +transformers/models/musicgen_melody/feature_extraction_musicgen_melody.py,sha256=u7RdsQUkosd0vDq5y4AQjxDj_NphdFOj3eR8juaSlG4,15232 +transformers/models/musicgen_melody/modeling_musicgen_melody.py,sha256=4l8_96ri5qeOgPOmek7c4PbWsykJncNYap6oq1L5jig,106039 +transformers/models/musicgen_melody/processing_musicgen_melody.py,sha256=jC5ueLR2V-SU3ZKPnW6RP9HVQOV4t6uHlIf0Ky4dR34,5024 +transformers/models/mvp/__init__.py,sha256=WZmfe74gf6cjN8OLNQ6ngkwTFzie-OV6VRPiAbBCTk8,1067 +transformers/models/mvp/__pycache__/__init__.cpython-310.pyc,, +transformers/models/mvp/__pycache__/configuration_mvp.cpython-310.pyc,, +transformers/models/mvp/__pycache__/modeling_mvp.cpython-310.pyc,, +transformers/models/mvp/configuration_mvp.py,sha256=BAL19VqriWm47u3qno-WP4fZ6D1x7RRA5KbPoCy4ul0,7888 +transformers/models/mvp/modeling_mvp.py,sha256=ZkogoyIvdDQTCkYlWty31sq3d5CqRGeoZzw5d7DQnJQ,73938 +transformers/models/myt5/__init__.py,sha256=MFQX-RuvZujGb_twBWBQpTt4NZq6FxreEysWmF2fFGI,955 +transformers/models/myt5/__pycache__/__init__.cpython-310.pyc,, +transformers/models/myt5/__pycache__/tokenization_myt5.cpython-310.pyc,, +transformers/models/myt5/tokenization_myt5.py,sha256=9x5iRVCKPjao8zsLbD5_8ACxZ9WLZtg59E1c7KmTk3s,15450 +transformers/models/nanochat/__init__.py,sha256=goJP7g0uNynZWyVMqvOWSR9yAOeWGSXbaUU8sq3aZhI,391 +transformers/models/nanochat/__pycache__/__init__.cpython-310.pyc,, +transformers/models/nanochat/__pycache__/configuration_nanochat.cpython-310.pyc,, +transformers/models/nanochat/__pycache__/modeling_nanochat.cpython-310.pyc,, +transformers/models/nanochat/__pycache__/modular_nanochat.cpython-310.pyc,, +transformers/models/nanochat/configuration_nanochat.py,sha256=m4wV4C8BEHX9Wx4gA-_yGp-dhE7ucgjPqwhKjd73pUo,7579 +transformers/models/nanochat/modeling_nanochat.py,sha256=i30AMECJVu5LdCE6Y707_3aOtTlv-7y30Jlbc3J5Kb0,22352 +transformers/models/nanochat/modular_nanochat.py,sha256=TL-I8s-rFikhLrMQkTWTNsx1XDAcAyDiYczBUhtlHJo,8961 +transformers/models/nemotron/__init__.py,sha256=ZwaMH1AQ0VIuFnouYe0Sx0HcCGA7PaCp3-_yw3xjeQA,997 +transformers/models/nemotron/__pycache__/__init__.cpython-310.pyc,, +transformers/models/nemotron/__pycache__/configuration_nemotron.cpython-310.pyc,, +transformers/models/nemotron/__pycache__/modeling_nemotron.cpython-310.pyc,, +transformers/models/nemotron/configuration_nemotron.py,sha256=MuT82l8mTpaiEg5IZ3QAv3uoVuk-wZXZNRj6X3HpYQU,7732 +transformers/models/nemotron/modeling_nemotron.py,sha256=Kk2GC1LCGJnBZHEcHe_RFCfG850TsV57Tca64xZJOAA,36504 +transformers/models/nemotron_h/__init__.py,sha256=7AJceTeyBHQBpH9DWo9mqe2hUYiHsfQmp0TJiap83T4,1001 +transformers/models/nemotron_h/__pycache__/__init__.cpython-310.pyc,, +transformers/models/nemotron_h/__pycache__/configuration_nemotron_h.cpython-310.pyc,, +transformers/models/nemotron_h/__pycache__/modeling_nemotron_h.cpython-310.pyc,, +transformers/models/nemotron_h/__pycache__/modular_nemotron_h.cpython-310.pyc,, +transformers/models/nemotron_h/configuration_nemotron_h.py,sha256=D8gYwQUGyRvQLfWmBfScsHBLVJiVT0bb3i1jmZrjbD0,19822 +transformers/models/nemotron_h/modeling_nemotron_h.py,sha256=W81sKaFeMeCA4u9cZPaEV8VLfS22dCHg6osiIOpZi9o,64449 +transformers/models/nemotron_h/modular_nemotron_h.py,sha256=1VdNC8v0sHi8KTrP-VTx5sJkMIH8sCpBs4-fu52fjrM,24114 +transformers/models/nllb/__init__.py,sha256=fBkcHp1TFP4bRdUvTzwZf2syVKJZul8cTf5csjI2EbY,955 +transformers/models/nllb/__pycache__/__init__.cpython-310.pyc,, +transformers/models/nllb/__pycache__/tokenization_nllb.cpython-310.pyc,, +transformers/models/nllb/tokenization_nllb.py,sha256=KP3SB1ew5El3j09KmHMrzSf8YPSF9DUf7rt7uvcVC-4,14688 +transformers/models/nllb_moe/__init__.py,sha256=sAfoAnhHK_reU1a2WUoF1rFtPBckeGGrzJCD8gUv54A,997 +transformers/models/nllb_moe/__pycache__/__init__.cpython-310.pyc,, +transformers/models/nllb_moe/__pycache__/configuration_nllb_moe.cpython-310.pyc,, +transformers/models/nllb_moe/__pycache__/modeling_nllb_moe.cpython-310.pyc,, +transformers/models/nllb_moe/configuration_nllb_moe.py,sha256=WYB31JSUTZ0yq4JsdiJLJuL4Siu14Ovp634K7gdYCwc,11269 +transformers/models/nllb_moe/modeling_nllb_moe.py,sha256=obxrd4UhW4ALDQdPwxUj6qdShPIOn1xUPAwC-wYiy30,50279 +transformers/models/nougat/__init__.py,sha256=NR2EgftVRP0ltdLWEhgsjaw3PbxG21vwy9pb9-hWTdQ,1085 +transformers/models/nougat/__pycache__/__init__.cpython-310.pyc,, +transformers/models/nougat/__pycache__/image_processing_nougat.cpython-310.pyc,, +transformers/models/nougat/__pycache__/image_processing_nougat_fast.cpython-310.pyc,, +transformers/models/nougat/__pycache__/processing_nougat.cpython-310.pyc,, +transformers/models/nougat/__pycache__/tokenization_nougat.cpython-310.pyc,, +transformers/models/nougat/image_processing_nougat.py,sha256=6SCJUGkSf9Nv2FY4wfxkRWkdJ1WOH7ojCrmj8CiqRZ0,24381 +transformers/models/nougat/image_processing_nougat_fast.py,sha256=DtteJ3wfzpqdWhDR15gXlcJt7VPl74QIG1t6CzEc1fo,10574 +transformers/models/nougat/processing_nougat.py,sha256=TtuqEqsaYGsPHbGvkVABcux50-fxA8bFpkV5ckA_k9Q,6221 +transformers/models/nougat/tokenization_nougat.py,sha256=pCewH677NvZQAokX0nR7ya3qM7h_5LaYST4OBNunwk4,26091 +transformers/models/nystromformer/__init__.py,sha256=CwEg6m4nJW_AfNDws_MIv1O1x5IO3xPp-FYqirlFXwk,1007 +transformers/models/nystromformer/__pycache__/__init__.cpython-310.pyc,, +transformers/models/nystromformer/__pycache__/configuration_nystromformer.cpython-310.pyc,, +transformers/models/nystromformer/__pycache__/modeling_nystromformer.cpython-310.pyc,, +transformers/models/nystromformer/configuration_nystromformer.py,sha256=--0aacEb6KLruQqNkmBLHgSUocxjg2CDWDN2O-LJQmk,6608 +transformers/models/nystromformer/modeling_nystromformer.py,sha256=jJBI7FkkDu3noXURcBinuk2iY2AeRrWK2cjVusZr9wI,39903 +transformers/models/olmo/__init__.py,sha256=x9u_5vqI52-uBuj89-6aYucGDlvBUEPSOhPLLB1asok,1009 +transformers/models/olmo/__pycache__/__init__.cpython-310.pyc,, +transformers/models/olmo/__pycache__/configuration_olmo.cpython-310.pyc,, +transformers/models/olmo/__pycache__/modeling_olmo.cpython-310.pyc,, +transformers/models/olmo/__pycache__/modular_olmo.cpython-310.pyc,, +transformers/models/olmo/configuration_olmo.py,sha256=0b55q1arKaQCE_MlQI2T7FmdYWKLxhU_q5KN36RssGY,8097 +transformers/models/olmo/modeling_olmo.py,sha256=Xii6pi-Dq14_S3VUHCMbnCtE3UuKT254yylcaV6U3xU,21803 +transformers/models/olmo/modular_olmo.py,sha256=lwudPe6bFW4Swj7AFNZ9j4iMKex2OFr-W0s-y-68xm0,7903 +transformers/models/olmo2/__init__.py,sha256=Frt9nEMsfPszod1lkFTAJUobU50IjOFlqI6uJkuQVcY,1011 +transformers/models/olmo2/__pycache__/__init__.cpython-310.pyc,, +transformers/models/olmo2/__pycache__/configuration_olmo2.cpython-310.pyc,, +transformers/models/olmo2/__pycache__/modeling_olmo2.cpython-310.pyc,, +transformers/models/olmo2/__pycache__/modular_olmo2.cpython-310.pyc,, +transformers/models/olmo2/configuration_olmo2.py,sha256=mPrW-RhiSPRhZxF6FKf5XO-3aLUGsBG9exUOG5Sfu_Y,9058 +transformers/models/olmo2/modeling_olmo2.py,sha256=8se0M94selIyFX5052nNJ5xxtBxZdES4xgwplLtTdEk,22236 +transformers/models/olmo2/modular_olmo2.py,sha256=pGmS_A0plaYz_EmXEq9Fc_TnFrQnLTxjYrThmN3p4Nk,14556 +transformers/models/olmo3/__init__.py,sha256=NpEGa6NN749b7p7EtG9F8yf6oGweZ6wQZZ8-6YEzjL4,992 +transformers/models/olmo3/__pycache__/__init__.cpython-310.pyc,, +transformers/models/olmo3/__pycache__/configuration_olmo3.cpython-310.pyc,, +transformers/models/olmo3/__pycache__/modeling_olmo3.cpython-310.pyc,, +transformers/models/olmo3/__pycache__/modular_olmo3.cpython-310.pyc,, +transformers/models/olmo3/configuration_olmo3.py,sha256=zGGHFevUyCU1ohck8e4qoYYUKA4ejEPtRIF2GORs0fA,9566 +transformers/models/olmo3/modeling_olmo3.py,sha256=XNGP02HdzhugYAakd1sJTF3yiobteGBX_5AefFGWOi4,22658 +transformers/models/olmo3/modular_olmo3.py,sha256=GHs6IimU1GtmTPcaJJaiScl-C9xAp8onZs_q3H-R0S0,15599 +transformers/models/olmo_hybrid/__init__.py,sha256=wvEIP-_OKmosjwUvlG8svHclHwvGstxHHCHLkkJYZ1k,1004 +transformers/models/olmo_hybrid/__pycache__/__init__.cpython-310.pyc,, +transformers/models/olmo_hybrid/__pycache__/configuration_olmo_hybrid.cpython-310.pyc,, +transformers/models/olmo_hybrid/__pycache__/modeling_olmo_hybrid.cpython-310.pyc,, +transformers/models/olmo_hybrid/__pycache__/modular_olmo_hybrid.cpython-310.pyc,, +transformers/models/olmo_hybrid/configuration_olmo_hybrid.py,sha256=b1pvk0RYrrVe1-6pC_ufwJRlfVFIwCepq4uQro8Miao,13351 +transformers/models/olmo_hybrid/modeling_olmo_hybrid.py,sha256=3iycL9tWUgodwr0ECAjpVmv0TCAy-vHCbD4Z1xaE5FM,48214 +transformers/models/olmo_hybrid/modular_olmo_hybrid.py,sha256=7GWy5blDXhNXgba2cfgbluONUPFahvHhPjW-pCJmx18,36988 +transformers/models/olmoe/__init__.py,sha256=eQ6mx9aBIcA4RiK3p7dbqORokkuMfQNRss06E8uWNrk,991 +transformers/models/olmoe/__pycache__/__init__.cpython-310.pyc,, +transformers/models/olmoe/__pycache__/configuration_olmoe.cpython-310.pyc,, +transformers/models/olmoe/__pycache__/modeling_olmoe.cpython-310.pyc,, +transformers/models/olmoe/__pycache__/modular_olmoe.cpython-310.pyc,, +transformers/models/olmoe/configuration_olmoe.py,sha256=-u6ERudu-PWSsODTwVlKGlzNco5AmfpVsAZ8baVbhCA,8578 +transformers/models/olmoe/modeling_olmoe.py,sha256=VeH5-7Cr1fm3hzD62tDUMbilIbvXN_lr6EUks1vZ-DM,31661 +transformers/models/olmoe/modular_olmoe.py,sha256=qpLVKpDYk3U1EsiuxII-pS8VVyp99Ia-DORfmATTCt0,11466 +transformers/models/omdet_turbo/__init__.py,sha256=XIckpuo9tkT7NB5uTs9wLdpxr9GDedQPVJL2P8XU-7Q,1045 +transformers/models/omdet_turbo/__pycache__/__init__.cpython-310.pyc,, +transformers/models/omdet_turbo/__pycache__/configuration_omdet_turbo.cpython-310.pyc,, +transformers/models/omdet_turbo/__pycache__/modeling_omdet_turbo.cpython-310.pyc,, +transformers/models/omdet_turbo/__pycache__/processing_omdet_turbo.cpython-310.pyc,, +transformers/models/omdet_turbo/configuration_omdet_turbo.py,sha256=IF_uqMuWfLWLV2xmh8sActnhE73FxH9YqhifVBxoLHA,12885 +transformers/models/omdet_turbo/modeling_omdet_turbo.py,sha256=HgEEyiuNKvrA574qedH3ASWD-cRmX5wK4gaRJ2bOQLA,74320 +transformers/models/omdet_turbo/processing_omdet_turbo.py,sha256=0ZP_V3gWR0KQqykY1_2LQv3jk4jx5n0MFvrRLNSf468,14342 +transformers/models/oneformer/__init__.py,sha256=MrdVp7ZBJOVbWMpwojOPnEzDDW2HSqs5oSZG81jdCQI,1136 +transformers/models/oneformer/__pycache__/__init__.cpython-310.pyc,, +transformers/models/oneformer/__pycache__/configuration_oneformer.cpython-310.pyc,, +transformers/models/oneformer/__pycache__/image_processing_oneformer.cpython-310.pyc,, +transformers/models/oneformer/__pycache__/image_processing_oneformer_fast.cpython-310.pyc,, +transformers/models/oneformer/__pycache__/modeling_oneformer.cpython-310.pyc,, +transformers/models/oneformer/__pycache__/processing_oneformer.cpython-310.pyc,, +transformers/models/oneformer/configuration_oneformer.py,sha256=XT4d6nuS0TGLmIXQRvsaSNtgDGPMA0basR-wleMUaAo,11337 +transformers/models/oneformer/image_processing_oneformer.py,sha256=oDf_6jWU0pjKWrp4T3XT3tQb3PVC7vrfp8nc8AdBYYw,61082 +transformers/models/oneformer/image_processing_oneformer_fast.py,sha256=t6MPovYB512EAkQVkZdr9z3DxRssea-JMHex1y6vp8s,39918 +transformers/models/oneformer/modeling_oneformer.py,sha256=E5mnC4XQOGBklk_sl2zjtLDADgvrvQQ9kO2MXYQ-FWU,138375 +transformers/models/oneformer/processing_oneformer.py,sha256=xU3fmwOzcxir0Q2RPP23mRL_jKG6TBKjAd4hbnIKFgs,8231 +transformers/models/openai/__init__.py,sha256=6Xrt4E8F9t4MlKOmv-zaguA_Vx93QCHsYLCVVtAONvQ,1032 +transformers/models/openai/__pycache__/__init__.cpython-310.pyc,, +transformers/models/openai/__pycache__/configuration_openai.cpython-310.pyc,, +transformers/models/openai/__pycache__/modeling_openai.cpython-310.pyc,, +transformers/models/openai/__pycache__/tokenization_openai.cpython-310.pyc,, +transformers/models/openai/configuration_openai.py,sha256=0v4pFWsLhqyOiKAQjfLy0DUbxPLxrEikv1BCDbqV3Q4,7686 +transformers/models/openai/modeling_openai.py,sha256=9WiylUqC4Wbb8lXP6TKzqSuWQoJqRSnDRswc96gVCzw,31961 +transformers/models/openai/tokenization_openai.py,sha256=-DIP7TMkKZ057AEdSRt6G-oi7JUQvlZhvAZT245QdiM,3593 +transformers/models/opt/__init__.py,sha256=CiUBzuuyvAs-mBmRsBpCbMjI8ATPNgUMzzqEl5VhkIk,987 +transformers/models/opt/__pycache__/__init__.cpython-310.pyc,, +transformers/models/opt/__pycache__/configuration_opt.cpython-310.pyc,, +transformers/models/opt/__pycache__/modeling_opt.cpython-310.pyc,, +transformers/models/opt/configuration_opt.py,sha256=lV5nfoawjnjnSK1Mf-DMSc0kkTIslkhLRCWNRwyFZ-U,6751 +transformers/models/opt/modeling_opt.py,sha256=LJqvmib1fWH-D2l1alM4vFR4thbEovUn87OcnPyo6B8,39313 +transformers/models/ovis2/__init__.py,sha256=HwxC8kFIZohrCDX0F9PYW8dH9R0OEnSnx5LNpXmA_Y4,1122 +transformers/models/ovis2/__pycache__/__init__.cpython-310.pyc,, +transformers/models/ovis2/__pycache__/configuration_ovis2.cpython-310.pyc,, +transformers/models/ovis2/__pycache__/image_processing_ovis2.cpython-310.pyc,, +transformers/models/ovis2/__pycache__/image_processing_ovis2_fast.cpython-310.pyc,, +transformers/models/ovis2/__pycache__/modeling_ovis2.cpython-310.pyc,, +transformers/models/ovis2/__pycache__/modular_ovis2.cpython-310.pyc,, +transformers/models/ovis2/__pycache__/processing_ovis2.cpython-310.pyc,, +transformers/models/ovis2/configuration_ovis2.py,sha256=KQlHaSM_Std4zbCRJ4_ATNBPHJqqsRbtpVnEnDLRpjw,8376 +transformers/models/ovis2/image_processing_ovis2.py,sha256=NS1pVMsAsEPCP777v8NtKMOuoSC4ng_ZxicErSfmgDU,28736 +transformers/models/ovis2/image_processing_ovis2_fast.py,sha256=MIjedbugEImKf2AZYBbmPfR3NrbwUCWCr4oMbxNil6M,9334 +transformers/models/ovis2/modeling_ovis2.py,sha256=_Y-HXQU26gAxf0jV-4mNFiNAh4yn_oi5WKeYKm-5geg,32497 +transformers/models/ovis2/modular_ovis2.py,sha256=wG4XFk7PbhTNpExgLLMAppsNVXwLOnbU7-SSy-WHIp4,19100 +transformers/models/ovis2/processing_ovis2.py,sha256=n8aFkT7PlZhJSsEAsZZHR8fs1ni33hyQMP_Jh4xPchw,5847 +transformers/models/owlv2/__init__.py,sha256=vHnQwYJ0hEc12ofOV3b1k9fHscBgfQEXcLLgo4-H3GU,1116 +transformers/models/owlv2/__pycache__/__init__.cpython-310.pyc,, +transformers/models/owlv2/__pycache__/configuration_owlv2.cpython-310.pyc,, +transformers/models/owlv2/__pycache__/image_processing_owlv2.cpython-310.pyc,, +transformers/models/owlv2/__pycache__/image_processing_owlv2_fast.cpython-310.pyc,, +transformers/models/owlv2/__pycache__/modeling_owlv2.cpython-310.pyc,, +transformers/models/owlv2/__pycache__/modular_owlv2.cpython-310.pyc,, +transformers/models/owlv2/__pycache__/processing_owlv2.cpython-310.pyc,, +transformers/models/owlv2/configuration_owlv2.py,sha256=LSWfo-J9ioi7TIwlJ8-Uixf-yIeWMAonLx1JOyhM_74,12836 +transformers/models/owlv2/image_processing_owlv2.py,sha256=EI7_Pr4RutS7fZ3QMzfZ5zK5StP8uu3C6d97RIs3j_c,27632 +transformers/models/owlv2/image_processing_owlv2_fast.py,sha256=_EApqIg6b0b39alnq6C1J8CgbCGXUPrOFyD0jVuK1fs,15231 +transformers/models/owlv2/modeling_owlv2.py,sha256=3mLL874BaLLN6JoXp0AisJkuSoqRUyeE_pePhMWk9qo,77096 +transformers/models/owlv2/modular_owlv2.py,sha256=PjF6GJTQ-yQAr4ZHvpC87qT6yubfN8Oj374BgOB25u0,8006 +transformers/models/owlv2/processing_owlv2.py,sha256=4YYmsD3J5I7LlcOTz9HCL5RTFiPMncBjvzYUsEs0sAY,10439 +transformers/models/owlvit/__init__.py,sha256=Nhrrja_j2RZtj-rQS6TDJ8upQqnMptnFukq49QAkito,1166 +transformers/models/owlvit/__pycache__/__init__.cpython-310.pyc,, +transformers/models/owlvit/__pycache__/configuration_owlvit.cpython-310.pyc,, +transformers/models/owlvit/__pycache__/image_processing_owlvit.cpython-310.pyc,, +transformers/models/owlvit/__pycache__/image_processing_owlvit_fast.cpython-310.pyc,, +transformers/models/owlvit/__pycache__/modeling_owlvit.cpython-310.pyc,, +transformers/models/owlvit/__pycache__/processing_owlvit.cpython-310.pyc,, +transformers/models/owlvit/configuration_owlvit.py,sha256=_yIPreNO8Rz0dlUUivGxHb1YNzdJf1mOJ0n1nsp2P48,12382 +transformers/models/owlvit/image_processing_owlvit.py,sha256=YBz63bSKLvKovKU_ah4qkJLCjykv879YKN115UPGuZk,26870 +transformers/models/owlvit/image_processing_owlvit_fast.py,sha256=cl6jw6x2U7SFFQIPYB0Keuh_gtKMyQUHWrypSWNXEbw,8178 +transformers/models/owlvit/modeling_owlvit.py,sha256=dl381YDb8EaLE-1TVkOq8Y-B5YPcIuQ0LuydtkBZ2NU,72555 +transformers/models/owlvit/processing_owlvit.py,sha256=mNqcLhleQR-oBxPd7Z1CfT3YnHghJlm7gLSIGtiF3hM,10389 +transformers/models/paddleocr_vl/__init__.py,sha256=2FIAOeLbqCTbEEzHOM5Gh0i-WQOkrZOFyhRof2fZzaQ,1152 +transformers/models/paddleocr_vl/__pycache__/__init__.cpython-310.pyc,, +transformers/models/paddleocr_vl/__pycache__/configuration_paddleocr_vl.cpython-310.pyc,, +transformers/models/paddleocr_vl/__pycache__/image_processing_paddleocr_vl.cpython-310.pyc,, +transformers/models/paddleocr_vl/__pycache__/image_processing_paddleocr_vl_fast.cpython-310.pyc,, +transformers/models/paddleocr_vl/__pycache__/modeling_paddleocr_vl.cpython-310.pyc,, +transformers/models/paddleocr_vl/__pycache__/modular_paddleocr_vl.cpython-310.pyc,, +transformers/models/paddleocr_vl/__pycache__/processing_paddleocr_vl.cpython-310.pyc,, +transformers/models/paddleocr_vl/configuration_paddleocr_vl.py,sha256=hDURucEtFDchNVGKbV_dpNDhacx_9orZ4V0fwQVgeVE,16640 +transformers/models/paddleocr_vl/image_processing_paddleocr_vl.py,sha256=Bl3TC6pqtklrkVEiylYVZyabJpGZxAVSdutPq8Ni38s,25011 +transformers/models/paddleocr_vl/image_processing_paddleocr_vl_fast.py,sha256=sEMvmLsh4JRugNKrzHOrZuDx--DNDcDvbayGpJaSAGw,9298 +transformers/models/paddleocr_vl/modeling_paddleocr_vl.py,sha256=FAh9VDXJqVBbKbqGBma8sngWkZDtTUVO3qVPpVeicPY,79341 +transformers/models/paddleocr_vl/modular_paddleocr_vl.py,sha256=JxEx2fzAzQnTyoGN1oGqcuAvhBx4te25bNj2AsflG9o,60077 +transformers/models/paddleocr_vl/processing_paddleocr_vl.py,sha256=nOXUfMQd9zUWA48-TXXG7WNpwBoZukBfMvbDTmYEYq4,7307 +transformers/models/paligemma/__init__.py,sha256=nKnTTLC8XYlI7uYfS8h-D4vz3gFhknkNeDlZIwZlZ9w,1039 +transformers/models/paligemma/__pycache__/__init__.cpython-310.pyc,, +transformers/models/paligemma/__pycache__/configuration_paligemma.cpython-310.pyc,, +transformers/models/paligemma/__pycache__/modeling_paligemma.cpython-310.pyc,, +transformers/models/paligemma/__pycache__/processing_paligemma.cpython-310.pyc,, +transformers/models/paligemma/configuration_paligemma.py,sha256=_yKP-wd4C6Q1tt3VaMxgDEkefVFMwi0IiCoV-yYsF1g,5883 +transformers/models/paligemma/modeling_paligemma.py,sha256=2oo-KuJPHQEG3V9lc6s-GabCfrVYlOwg1HlHFEqzOmE,27483 +transformers/models/paligemma/processing_paligemma.py,sha256=1bunlD42ZYjO8k-txXz6-tM3DvR6E5MghcnhrC2U_Dk,11657 +transformers/models/parakeet/__init__.py,sha256=hUBWAelpUTDzNsO6U5c1w2mts5ePvfNbov_OzhNh8X4,1090 +transformers/models/parakeet/__pycache__/__init__.cpython-310.pyc,, +transformers/models/parakeet/__pycache__/configuration_parakeet.cpython-310.pyc,, +transformers/models/parakeet/__pycache__/feature_extraction_parakeet.cpython-310.pyc,, +transformers/models/parakeet/__pycache__/modeling_parakeet.cpython-310.pyc,, +transformers/models/parakeet/__pycache__/modular_parakeet.cpython-310.pyc,, +transformers/models/parakeet/__pycache__/processing_parakeet.cpython-310.pyc,, +transformers/models/parakeet/__pycache__/tokenization_parakeet.cpython-310.pyc,, +transformers/models/parakeet/configuration_parakeet.py,sha256=waFRRo64gYZgchT_e8i8QIUlL-wjYcrcrUAd_Ere-A0,10231 +transformers/models/parakeet/feature_extraction_parakeet.py,sha256=rgPjYQrUS34yK3T70hK1HKPGN3Xn4SnnoIcR_v7uvQI,13060 +transformers/models/parakeet/modeling_parakeet.py,sha256=6NLft9kFcROETUh8LmdAWdNC8eE5HOkMgL_lxpywiw0,35162 +transformers/models/parakeet/modular_parakeet.py,sha256=NtlEhOQW0aROrTcoDqeg0ZivbXw2YHpx9NCibnVeb2c,27575 +transformers/models/parakeet/processing_parakeet.py,sha256=uunbJnQFnuXngkefqJysUUbXY7KycnS6e5_eXUh7Q3c,3688 +transformers/models/parakeet/tokenization_parakeet.py,sha256=8XBCL3RL_d1jqZTYYaZ_kKoO59-dh0wqyOH78GQc7Pc,1873 +transformers/models/patchtsmixer/__init__.py,sha256=deFjF_Tu67XcAcNHaq1PXO77N4kVW9wG80SnXBaeagE,1005 +transformers/models/patchtsmixer/__pycache__/__init__.cpython-310.pyc,, +transformers/models/patchtsmixer/__pycache__/configuration_patchtsmixer.cpython-310.pyc,, +transformers/models/patchtsmixer/__pycache__/modeling_patchtsmixer.cpython-310.pyc,, +transformers/models/patchtsmixer/configuration_patchtsmixer.py,sha256=4Dr2wrQNc5O0cbJEVeXl3MEMDgvRdSSFaWbpiW_pha4,12168 +transformers/models/patchtsmixer/modeling_patchtsmixer.py,sha256=ByD4pMa8vGrImgwwXc69Fdeu4l_x7mCFrjS0C0D1Zvs,84971 +transformers/models/patchtst/__init__.py,sha256=lrpuBvP25Yq6HZOCyS4yWVYZ47qWzK--rqC0AOIGGPE,997 +transformers/models/patchtst/__pycache__/__init__.cpython-310.pyc,, +transformers/models/patchtst/__pycache__/configuration_patchtst.cpython-310.pyc,, +transformers/models/patchtst/__pycache__/modeling_patchtst.cpython-310.pyc,, +transformers/models/patchtst/configuration_patchtst.py,sha256=Oucc9IBZOeaQEes5r4YI2Gt4ahbhKzmDLoC6TNTijD0,12228 +transformers/models/patchtst/modeling_patchtst.py,sha256=PW20B9IfpYhmFU4QNt09nLradBwhlXBQFSo--KVVGuY,85005 +transformers/models/pe_audio/__init__.py,sha256=kPx9mIPU77pDtiJYg4xOr3RFIz_cUYBbToLt0dfC4k8,1088 +transformers/models/pe_audio/__pycache__/__init__.cpython-310.pyc,, +transformers/models/pe_audio/__pycache__/configuration_pe_audio.cpython-310.pyc,, +transformers/models/pe_audio/__pycache__/feature_extraction_pe_audio.cpython-310.pyc,, +transformers/models/pe_audio/__pycache__/modeling_pe_audio.cpython-310.pyc,, +transformers/models/pe_audio/__pycache__/modular_pe_audio.cpython-310.pyc,, +transformers/models/pe_audio/__pycache__/processing_pe_audio.cpython-310.pyc,, +transformers/models/pe_audio/configuration_pe_audio.py,sha256=rptnZixlKXsbI4AvvFSDSVKRU5NM6-PtGIY6Rhvspr8,8766 +transformers/models/pe_audio/feature_extraction_pe_audio.py,sha256=EzwR1sqIA2h1fr8VflbeFujIbnajl_0oUUEeuhov62o,6484 +transformers/models/pe_audio/modeling_pe_audio.py,sha256=FTO_l4VPam8zJp6DznAmXLOwExPSCO5oMmXHNRNmOfU,33045 +transformers/models/pe_audio/modular_pe_audio.py,sha256=85s62fMLPCCPe7J7EcZOq78sWXpkA-Gyba1HVm-I-UE,11380 +transformers/models/pe_audio/processing_pe_audio.py,sha256=DGJ-IjGrDuYgn9eSlH0s-l2nsrmQzh-e8sMBGvBf4hM,879 +transformers/models/pe_audio_video/__init__.py,sha256=tt4bWq6NXVc6hA7uTtMYQ3CD9APPTUlhUrPwpOKl22k,1059 +transformers/models/pe_audio_video/__pycache__/__init__.cpython-310.pyc,, +transformers/models/pe_audio_video/__pycache__/configuration_pe_audio_video.cpython-310.pyc,, +transformers/models/pe_audio_video/__pycache__/modeling_pe_audio_video.cpython-310.pyc,, +transformers/models/pe_audio_video/__pycache__/modular_pe_audio_video.cpython-310.pyc,, +transformers/models/pe_audio_video/__pycache__/processing_pe_audio_video.cpython-310.pyc,, +transformers/models/pe_audio_video/configuration_pe_audio_video.py,sha256=BKkqKs1nRhAiOoR_BggqNrZ1oN0duVL4oLqnBYKDDwU,9742 +transformers/models/pe_audio_video/modeling_pe_audio_video.py,sha256=tT9lK1nB_QFEIhxwqs_97PHv5wvKmcrfHqCBDnziK3o,42545 +transformers/models/pe_audio_video/modular_pe_audio_video.py,sha256=JSpvBp1gc5W_MYMUI1BnZH91qS0mDHgngYr9QhAM1vI,32526 +transformers/models/pe_audio_video/processing_pe_audio_video.py,sha256=ZlWrgf_y_zgW8waV4194VBAAcioM6fz6OGQUucezpBo,960 +transformers/models/pe_video/__init__.py,sha256=vCPdJDp9o_fTkcffIBjSBjuOqHM-PRhS5jf74KcKQdk,1086 +transformers/models/pe_video/__pycache__/__init__.cpython-310.pyc,, +transformers/models/pe_video/__pycache__/configuration_pe_video.cpython-310.pyc,, +transformers/models/pe_video/__pycache__/modeling_pe_video.cpython-310.pyc,, +transformers/models/pe_video/__pycache__/modular_pe_video.cpython-310.pyc,, +transformers/models/pe_video/__pycache__/processing_pe_video.cpython-310.pyc,, +transformers/models/pe_video/__pycache__/video_processing_pe_video.cpython-310.pyc,, +transformers/models/pe_video/configuration_pe_video.py,sha256=g86covIsYvHL5suYSjKWLDKAKVAWxLJwGoufO6EJHc0,8993 +transformers/models/pe_video/modeling_pe_video.py,sha256=CC2-FhM3hY7mVD8VsB1VHg3MH7c7q6jTTN3qah0gXP8,26657 +transformers/models/pe_video/modular_pe_video.py,sha256=fnl6-8DG1kMsAj7PRGouH-u34fRJ5p08MXeNtTt4bjY,8873 +transformers/models/pe_video/processing_pe_video.py,sha256=ZrP95LzdcixtU5U_ZjcgKRCHnbH4_35SoFhyCSXtNwI,262 +transformers/models/pe_video/video_processing_pe_video.py,sha256=v04MsBAnyhLJfIkd2iZL6PROPIdiuYsE2R6bOKnCoFE,2663 +transformers/models/pegasus/__init__.py,sha256=jCo_uusFhqSgC-X8TuopKyGESiE96TLPuo7ooxzMx2M,1035 +transformers/models/pegasus/__pycache__/__init__.cpython-310.pyc,, +transformers/models/pegasus/__pycache__/configuration_pegasus.cpython-310.pyc,, +transformers/models/pegasus/__pycache__/modeling_pegasus.cpython-310.pyc,, +transformers/models/pegasus/__pycache__/tokenization_pegasus.cpython-310.pyc,, +transformers/models/pegasus/configuration_pegasus.py,sha256=Ey83j4LK-WiyMEiz-LICTA5gTELPlPNWhNX_1t0_oUQ,7462 +transformers/models/pegasus/modeling_pegasus.py,sha256=l2XKB93pw4Rpzjln0lx0ZXOAkCvRQArlvUTH-YICmt8,61668 +transformers/models/pegasus/tokenization_pegasus.py,sha256=o2g40foldbLBL13qGkYXH7lg69AewPvARD-c9-hoewQ,6427 +transformers/models/pegasus_x/__init__.py,sha256=qSLaqKRA1upZOobapHW5MjSZvIEzf-ij-ZmY1VGzqaE,999 +transformers/models/pegasus_x/__pycache__/__init__.cpython-310.pyc,, +transformers/models/pegasus_x/__pycache__/configuration_pegasus_x.cpython-310.pyc,, +transformers/models/pegasus_x/__pycache__/modeling_pegasus_x.cpython-310.pyc,, +transformers/models/pegasus_x/configuration_pegasus_x.py,sha256=S9lVxUPcvviUd4qlV2Ue7iSoCfhDhu4E-7NfCP_Dbs0,8034 +transformers/models/pegasus_x/modeling_pegasus_x.py,sha256=pDmSvqeGg4KWXGVHmapyS_XU_bCkrFVwePAv3KsAEOI,67323 +transformers/models/perceiver/__init__.py,sha256=LKUlUJfZGRC1jU6TNkG-4kNy8aIeHIqvAnwLI_33AVY,1186 +transformers/models/perceiver/__pycache__/__init__.cpython-310.pyc,, +transformers/models/perceiver/__pycache__/configuration_perceiver.cpython-310.pyc,, +transformers/models/perceiver/__pycache__/image_processing_perceiver.cpython-310.pyc,, +transformers/models/perceiver/__pycache__/image_processing_perceiver_fast.cpython-310.pyc,, +transformers/models/perceiver/__pycache__/modeling_perceiver.cpython-310.pyc,, +transformers/models/perceiver/__pycache__/tokenization_perceiver.cpython-310.pyc,, +transformers/models/perceiver/configuration_perceiver.py,sha256=6VhJXpcTgpZX80UEOxl8ABUKY_axtP04b-i6EfPIZmI,8986 +transformers/models/perceiver/image_processing_perceiver.py,sha256=3ZV968wpP3NuFHWSQ7hspm_KPuAq7phLhlouB_3hnGY,17150 +transformers/models/perceiver/image_processing_perceiver_fast.py,sha256=ZuIZIII8al0rLUoFnU5n8b_vSvDYmavNwSD2x4_0VlU,4888 +transformers/models/perceiver/modeling_perceiver.py,sha256=_RW15BtDHfS7KZwHLE-dZ9Otr6NgNrHR8QIl9FNpSX0,134809 +transformers/models/perceiver/tokenization_perceiver.py,sha256=GVEoliqqJb7AtXDXRtjmp_45E-IJLoPZA8jNIgcHvP8,7982 +transformers/models/perception_lm/__init__.py,sha256=RVEjQWlzsHJm3D-3JXLThzBjJLSCMpvFslQMIkvRKiA,1106 +transformers/models/perception_lm/__pycache__/__init__.cpython-310.pyc,, +transformers/models/perception_lm/__pycache__/configuration_perception_lm.cpython-310.pyc,, +transformers/models/perception_lm/__pycache__/image_processing_perception_lm_fast.cpython-310.pyc,, +transformers/models/perception_lm/__pycache__/modeling_perception_lm.cpython-310.pyc,, +transformers/models/perception_lm/__pycache__/modular_perception_lm.cpython-310.pyc,, +transformers/models/perception_lm/__pycache__/processing_perception_lm.cpython-310.pyc,, +transformers/models/perception_lm/__pycache__/video_processing_perception_lm.cpython-310.pyc,, +transformers/models/perception_lm/configuration_perception_lm.py,sha256=6XjSd9WSh1orySWa40xP-xMmmQsCPgKvoE0fW5KzNpU,3873 +transformers/models/perception_lm/image_processing_perception_lm_fast.py,sha256=vfheD9pfofybGomiacPiZgBB7rzYpLQJnJVeweBK1RY,13806 +transformers/models/perception_lm/modeling_perception_lm.py,sha256=PW9jxAPp9cAZKEm-E_btd4VtE0D3-zFP5veI-9Xn2iY,21263 +transformers/models/perception_lm/modular_perception_lm.py,sha256=RoPcqRKERmMihIQBQh5rbeaXyNDMxjbyKPZMh05bDr4,18852 +transformers/models/perception_lm/processing_perception_lm.py,sha256=gRjgGRjmU25ON-eKddy3CB-I_FWE_-JhVOcl6mGQnUM,8828 +transformers/models/perception_lm/video_processing_perception_lm.py,sha256=i49-VYt3kgRhkf7XRyD3sYaoI2pIKCNSTlyXfzjnBPk,1211 +transformers/models/persimmon/__init__.py,sha256=T1WqyE78N2TO74u9a9QdRIGaMowYqP6vWv8KhPojkLg,999 +transformers/models/persimmon/__pycache__/__init__.cpython-310.pyc,, +transformers/models/persimmon/__pycache__/configuration_persimmon.cpython-310.pyc,, +transformers/models/persimmon/__pycache__/modeling_persimmon.cpython-310.pyc,, +transformers/models/persimmon/configuration_persimmon.py,sha256=mAdkyEBvTDIAFBn-eJgH5nDEnaiqiTwjTElwuSpx9Rc,6103 +transformers/models/persimmon/modeling_persimmon.py,sha256=8RLPAmQecl4PNXC3RtfCTCcQNivv3lSV1J1AoyhADeM,27400 +transformers/models/phi/__init__.py,sha256=4DUgmUqGKcGXxzTrxUVGcacZ43uv3SzXsOV_Ke6oeGg,1006 +transformers/models/phi/__pycache__/__init__.cpython-310.pyc,, +transformers/models/phi/__pycache__/configuration_phi.cpython-310.pyc,, +transformers/models/phi/__pycache__/modeling_phi.cpython-310.pyc,, +transformers/models/phi/__pycache__/modular_phi.cpython-310.pyc,, +transformers/models/phi/configuration_phi.py,sha256=DsZqkrnaBCFhyKwFxtoDg_NW_9wvyEZ_MbtcDtPA50Y,8304 +transformers/models/phi/modeling_phi.py,sha256=jAIu0h3qfJqfQesmDZaP1SKYLu4qMsLKI745VQmpjYo,23278 +transformers/models/phi/modular_phi.py,sha256=bU8Wd5A2yaoRleHusMVtTX9IlMJEV-LzJseeSXFNkw0,12736 +transformers/models/phi3/__init__.py,sha256=dxyO-jIh0yB6t2Dzs173aRrEnTceVMIYIkg6JxIeyWs,989 +transformers/models/phi3/__pycache__/__init__.cpython-310.pyc,, +transformers/models/phi3/__pycache__/configuration_phi3.cpython-310.pyc,, +transformers/models/phi3/__pycache__/modeling_phi3.cpython-310.pyc,, +transformers/models/phi3/__pycache__/modular_phi3.cpython-310.pyc,, +transformers/models/phi3/configuration_phi3.py,sha256=LUff5nDohJf31WJk1htAp464PozT2s_yaBLyruNABH0,12196 +transformers/models/phi3/modeling_phi3.py,sha256=h6UOi-ynmlBNowUCgC-XQIQMB0kZwKqJlk6Z1RQooIc,24379 +transformers/models/phi3/modular_phi3.py,sha256=RRwpm5PYINbS5KDsAq4rk4QHYvVujV6ByPr71xmv-1U,10809 +transformers/models/phi4_multimodal/__init__.py,sha256=EqoKUvkh9f14qg07g-4MLclztlyiyLfN2qqEp3RGp2w,1170 +transformers/models/phi4_multimodal/__pycache__/__init__.cpython-310.pyc,, +transformers/models/phi4_multimodal/__pycache__/configuration_phi4_multimodal.cpython-310.pyc,, +transformers/models/phi4_multimodal/__pycache__/feature_extraction_phi4_multimodal.cpython-310.pyc,, +transformers/models/phi4_multimodal/__pycache__/image_processing_phi4_multimodal_fast.cpython-310.pyc,, +transformers/models/phi4_multimodal/__pycache__/modeling_phi4_multimodal.cpython-310.pyc,, +transformers/models/phi4_multimodal/__pycache__/modular_phi4_multimodal.cpython-310.pyc,, +transformers/models/phi4_multimodal/__pycache__/processing_phi4_multimodal.cpython-310.pyc,, +transformers/models/phi4_multimodal/configuration_phi4_multimodal.py,sha256=tgVbkM1-adIfkWFBBkxvd_I_HJh6Id7E-MK3hNUaLJY,25062 +transformers/models/phi4_multimodal/feature_extraction_phi4_multimodal.py,sha256=HDFWut0WDq1UnvOatGpJmlmVYTG0s6vEOYpW_JUd-3A,13283 +transformers/models/phi4_multimodal/image_processing_phi4_multimodal_fast.py,sha256=m172F56wOLW0X3wld-FRbV82Mt47hQIVlW3gSdDXSg4,10427 +transformers/models/phi4_multimodal/modeling_phi4_multimodal.py,sha256=x4NRZ2FseIqzKyHK8U_DRi9JeDsKGOr-eGrXBkS6jnw,77342 +transformers/models/phi4_multimodal/modular_phi4_multimodal.py,sha256=SLVU7BkKDXrAtAr05DShocAAPFNBVB9lpBHZo12udcw,77368 +transformers/models/phi4_multimodal/processing_phi4_multimodal.py,sha256=4V3Ehgv05ldiRZOUrA7YiaDwFAu9fKaGSA501LkT17c,5525 +transformers/models/phimoe/__init__.py,sha256=wGasPysu0EH_q0QGaZmXqQL57GxfZn8NTsvB2I6U2ro,1013 +transformers/models/phimoe/__pycache__/__init__.cpython-310.pyc,, +transformers/models/phimoe/__pycache__/configuration_phimoe.cpython-310.pyc,, +transformers/models/phimoe/__pycache__/modeling_phimoe.cpython-310.pyc,, +transformers/models/phimoe/__pycache__/modular_phimoe.cpython-310.pyc,, +transformers/models/phimoe/configuration_phimoe.py,sha256=2eXzxlzl4cjRAs3j1pbX3BT5VhmPD2PjQXbXXgSLTqk,10337 +transformers/models/phimoe/modeling_phimoe.py,sha256=wH--5_V1pDncuHPZHL6M04gKydwKJP3m9U7Yn_C2H0A,39411 +transformers/models/phimoe/modular_phimoe.py,sha256=6G5zo42B0TS-heG8ThG8-wW4RGJAfPQ2SJJEmzj8iEY,15642 +transformers/models/phobert/__init__.py,sha256=mau-2HIOzSk8qGIhxivVBPPYTx3hhdgoKPtnptDF38M,958 +transformers/models/phobert/__pycache__/__init__.cpython-310.pyc,, +transformers/models/phobert/__pycache__/tokenization_phobert.cpython-310.pyc,, +transformers/models/phobert/tokenization_phobert.py,sha256=WKrjnlFs4-Oh41kJMLDkdegGB50YKNAjooQY7WxxZ5E,13057 +transformers/models/pix2struct/__init__.py,sha256=nqs7D1WX64OUEJY7gRDIvAygxcnwhxlnEewOHLE9-O0,1141 +transformers/models/pix2struct/__pycache__/__init__.cpython-310.pyc,, +transformers/models/pix2struct/__pycache__/configuration_pix2struct.cpython-310.pyc,, +transformers/models/pix2struct/__pycache__/image_processing_pix2struct.cpython-310.pyc,, +transformers/models/pix2struct/__pycache__/image_processing_pix2struct_fast.cpython-310.pyc,, +transformers/models/pix2struct/__pycache__/modeling_pix2struct.cpython-310.pyc,, +transformers/models/pix2struct/__pycache__/processing_pix2struct.cpython-310.pyc,, +transformers/models/pix2struct/configuration_pix2struct.py,sha256=MWGhdyOvyJSVvSwy4Gf28nBRR3nMIo2kF67oARBUvkI,15862 +transformers/models/pix2struct/image_processing_pix2struct.py,sha256=X3kuH7EMc80gQPIzCjhpZ4h3T7yvptcBvM072Dnraxg,19918 +transformers/models/pix2struct/image_processing_pix2struct_fast.py,sha256=thtFvzgGBU0UUrX79D0f3qIBza9_Ls6eughecsRI3bE,13189 +transformers/models/pix2struct/modeling_pix2struct.py,sha256=-EWKgqJOgFrhIKxdRx_aCG0IkmCNKCLoc00DBX3lPB4,60770 +transformers/models/pix2struct/processing_pix2struct.py,sha256=GW-ZQSxH38270eh03EbjRm3nVT7sS4zFck7JwL2w-mk,4167 +transformers/models/pixio/__init__.py,sha256=G834ZPfjQ3fixXcSbc1mYJcb5FurIq7Ux5fYfD5ECGc,1041 +transformers/models/pixio/__pycache__/__init__.cpython-310.pyc,, +transformers/models/pixio/__pycache__/configuration_pixio.cpython-310.pyc,, +transformers/models/pixio/__pycache__/modeling_pixio.cpython-310.pyc,, +transformers/models/pixio/__pycache__/modular_pixio.cpython-310.pyc,, +transformers/models/pixio/configuration_pixio.py,sha256=hI7ZOugPjRzcs7pDvOmgbe5jwUm0kjtN3kSW77P1oHw,7832 +transformers/models/pixio/modeling_pixio.py,sha256=hUuixO8jtlnMke9Hx2_HWOVVORQKAIHH5OsNTat5GsY,21151 +transformers/models/pixio/modular_pixio.py,sha256=VZaCiVraLZwKp4Bb8pTOfScjIJaZN6J8RoY4dXEkt9s,16740 +transformers/models/pixtral/__init__.py,sha256=WKCxuWpCeTYsYSaTH1XnUcGkIHEx5BIIXwwwqG_E83s,1126 +transformers/models/pixtral/__pycache__/__init__.cpython-310.pyc,, +transformers/models/pixtral/__pycache__/configuration_pixtral.cpython-310.pyc,, +transformers/models/pixtral/__pycache__/image_processing_pixtral.cpython-310.pyc,, +transformers/models/pixtral/__pycache__/image_processing_pixtral_fast.cpython-310.pyc,, +transformers/models/pixtral/__pycache__/modeling_pixtral.cpython-310.pyc,, +transformers/models/pixtral/__pycache__/processing_pixtral.cpython-310.pyc,, +transformers/models/pixtral/configuration_pixtral.py,sha256=19KxBzXEZ77jkuA56zb_9fEb-b2T3JXNVfH4zJ4dZ4U,4453 +transformers/models/pixtral/image_processing_pixtral.py,sha256=YPXvB2KEcYufmYeDaknTNQU1uuCGVl88uFLDuGvjmMk,22088 +transformers/models/pixtral/image_processing_pixtral_fast.py,sha256=ShIuq__FzRkWUrykWO-HNbiHjOH-wQD96SFZl5J7esw,7418 +transformers/models/pixtral/modeling_pixtral.py,sha256=rGfEG6Lne1urZU0KT6Vonj0ojOnJW5gGgI3QlwENVbU,21907 +transformers/models/pixtral/processing_pixtral.py,sha256=oZHyKodZxm0dhYoK-YpTRfZVvxkeC6fry08Ic5V1Qio,9508 +transformers/models/plbart/__init__.py,sha256=jmP857QTG7jGfr9n0qK3TB_1-hdVDD1ajtJvP6C7FIw,1032 +transformers/models/plbart/__pycache__/__init__.cpython-310.pyc,, +transformers/models/plbart/__pycache__/configuration_plbart.cpython-310.pyc,, +transformers/models/plbart/__pycache__/modeling_plbart.cpython-310.pyc,, +transformers/models/plbart/__pycache__/modular_plbart.cpython-310.pyc,, +transformers/models/plbart/__pycache__/tokenization_plbart.cpython-310.pyc,, +transformers/models/plbart/configuration_plbart.py,sha256=2PXRu5XOiOOags31hLzI3cf_ramnk5x1lNP8q0lb2rE,7701 +transformers/models/plbart/modeling_plbart.py,sha256=FUA-hkkD51RyDT0CadR1ihSysrrq1X6lZC9Poa4qriE,63640 +transformers/models/plbart/modular_plbart.py,sha256=r4F02UA2V3NSTj9bwS5klv7HAYyRXeELPkk2oFTweD8,18769 +transformers/models/plbart/tokenization_plbart.py,sha256=lR3AaTrYtFQI-yoF_c8gilRh9XzRvGhukwTeY_FGwpI,15698 +transformers/models/poolformer/__init__.py,sha256=FgSXHIGeF8uz-Ye67HSRQefjounknzaqm0ZCOiMj4zo,1149 +transformers/models/poolformer/__pycache__/__init__.cpython-310.pyc,, +transformers/models/poolformer/__pycache__/configuration_poolformer.cpython-310.pyc,, +transformers/models/poolformer/__pycache__/image_processing_poolformer.cpython-310.pyc,, +transformers/models/poolformer/__pycache__/image_processing_poolformer_fast.cpython-310.pyc,, +transformers/models/poolformer/__pycache__/modeling_poolformer.cpython-310.pyc,, +transformers/models/poolformer/configuration_poolformer.py,sha256=-AOQSev1-Cgw3lvsTKnOJBLl8EAy8usPdGV56inufb8,5061 +transformers/models/poolformer/image_processing_poolformer.py,sha256=ivm6nSf5n33HzjH18bm4Jc4cHI8O90b99CFlKxczbZw,17874 +transformers/models/poolformer/image_processing_poolformer_fast.py,sha256=7tfl9sREG15Djf1O5DQrSxqNY9ktV67M3ww3PEtkBYo,9892 +transformers/models/poolformer/modeling_poolformer.py,sha256=2oiqSJbbPQDuts6pmdtirwhONIzOo3I5zNsKmTfcX1E,14459 +transformers/models/pop2piano/__init__.py,sha256=I2PPcFi-p0X5py7dLqobymv3E9g-mUv1QRn0luyPlIk,999 +transformers/models/pop2piano/__pycache__/__init__.cpython-310.pyc,, +transformers/models/pop2piano/__pycache__/configuration_pop2piano.cpython-310.pyc,, +transformers/models/pop2piano/__pycache__/feature_extraction_pop2piano.cpython-310.pyc,, +transformers/models/pop2piano/__pycache__/modeling_pop2piano.cpython-310.pyc,, +transformers/models/pop2piano/__pycache__/processing_pop2piano.cpython-310.pyc,, +transformers/models/pop2piano/__pycache__/tokenization_pop2piano.cpython-310.pyc,, +transformers/models/pop2piano/configuration_pop2piano.py,sha256=y_NPg9dFNLigd0g_cJQXTDzauDZj9F10SP-VNUC-n1E,6057 +transformers/models/pop2piano/feature_extraction_pop2piano.py,sha256=gwI8jIAeCX2P86gLyddK7Tqv11-4m3fxCk1sTToQl4s,19870 +transformers/models/pop2piano/modeling_pop2piano.py,sha256=8KZbNYYQm-ymRWGdE0L8IhprT3qaKvHp8aAr6cEMKg8,51699 +transformers/models/pop2piano/processing_pop2piano.py,sha256=Ufls4EQt6eAMcMuFhWnvJA4R-dshtRGKv-hiDoFYcIA,5235 +transformers/models/pop2piano/tokenization_pop2piano.py,sha256=cV3QqOZxqUG_5RpdOEktAOp73pRRu6Jeo6dJjqZCQek,32550 +transformers/models/pp_doclayout_v2/__init__.py,sha256=hYrwG1MZ1BT8lxp6zBCsdhPxW71qU60AXUo9-RBFk80,1070 +transformers/models/pp_doclayout_v2/__pycache__/__init__.cpython-310.pyc,, +transformers/models/pp_doclayout_v2/__pycache__/configuration_pp_doclayout_v2.cpython-310.pyc,, +transformers/models/pp_doclayout_v2/__pycache__/image_processing_pp_doclayout_v2_fast.cpython-310.pyc,, +transformers/models/pp_doclayout_v2/__pycache__/modeling_pp_doclayout_v2.cpython-310.pyc,, +transformers/models/pp_doclayout_v2/__pycache__/modular_pp_doclayout_v2.cpython-310.pyc,, +transformers/models/pp_doclayout_v2/configuration_pp_doclayout_v2.py,sha256=K5yvV0X5RD7wxBF4HIIaL5ilJk68oGBOU4RLVqh3hnY,21821 +transformers/models/pp_doclayout_v2/image_processing_pp_doclayout_v2_fast.py,sha256=LINQvHVgwLWqm3rDm-3dMdtQtWA8nDPbE_jwjj9f3RM,8834 +transformers/models/pp_doclayout_v2/modeling_pp_doclayout_v2.py,sha256=s_fO1cqBeRWAfzc4Yd54na02hwU26xJrPXvcrsYQPSc,115499 +transformers/models/pp_doclayout_v2/modular_pp_doclayout_v2.py,sha256=Yi0GO_pyopIOc3bIRx3GOW2rvIfmKXhUFEt0qLjSdlM,55352 +transformers/models/pp_doclayout_v3/__init__.py,sha256=NQrHEFooIN59S0_WZkfYR0YxizAgjVa8wdNGtOz6T1c,1070 +transformers/models/pp_doclayout_v3/__pycache__/__init__.cpython-310.pyc,, +transformers/models/pp_doclayout_v3/__pycache__/configuration_pp_doclayout_v3.cpython-310.pyc,, +transformers/models/pp_doclayout_v3/__pycache__/image_processing_pp_doclayout_v3_fast.cpython-310.pyc,, +transformers/models/pp_doclayout_v3/__pycache__/modeling_pp_doclayout_v3.cpython-310.pyc,, +transformers/models/pp_doclayout_v3/__pycache__/modular_pp_doclayout_v3.cpython-310.pyc,, +transformers/models/pp_doclayout_v3/configuration_pp_doclayout_v3.py,sha256=Gx7qqTfskWX0BnYXohiS0DkgA8Zs3X1xEU72VC35uVI,14646 +transformers/models/pp_doclayout_v3/image_processing_pp_doclayout_v3_fast.py,sha256=yzJgELSpBmq8JTm0pbphrVWVO3QQPfJwtmcQeZ3BOHU,13413 +transformers/models/pp_doclayout_v3/modeling_pp_doclayout_v3.py,sha256=al5_6SLEDx45yrCTi2AwrIq6HBFb8QeorQ8QixjZppk,95462 +transformers/models/pp_doclayout_v3/modular_pp_doclayout_v3.py,sha256=3Uo1VZWAE04ZZ1hRmtr7BAzSmaXd6rRea5UTXivkogE,74028 +transformers/models/prompt_depth_anything/__init__.py,sha256=KjyIVKAGtL4B0RRW4s5WyyFNmvimW_Cv36LkiyuPbGA,1333 +transformers/models/prompt_depth_anything/__pycache__/__init__.cpython-310.pyc,, +transformers/models/prompt_depth_anything/__pycache__/configuration_prompt_depth_anything.cpython-310.pyc,, +transformers/models/prompt_depth_anything/__pycache__/image_processing_prompt_depth_anything.cpython-310.pyc,, +transformers/models/prompt_depth_anything/__pycache__/image_processing_prompt_depth_anything_fast.cpython-310.pyc,, +transformers/models/prompt_depth_anything/__pycache__/modeling_prompt_depth_anything.cpython-310.pyc,, +transformers/models/prompt_depth_anything/__pycache__/modular_prompt_depth_anything.cpython-310.pyc,, +transformers/models/prompt_depth_anything/configuration_prompt_depth_anything.py,sha256=Wf7gnMQw4TIMNP0kXzFv75NzrlKZUXN2QTrtAROFiQg,6351 +transformers/models/prompt_depth_anything/image_processing_prompt_depth_anything.py,sha256=g0LoTQixD0sZim1WqljFE99_4XDiiVviH1tFA6V5hU4,25030 +transformers/models/prompt_depth_anything/image_processing_prompt_depth_anything_fast.py,sha256=9xk70kR_ldmYd8AgWQrHFr2MZgpQfL-x-pT0GUkfC9s,13209 +transformers/models/prompt_depth_anything/modeling_prompt_depth_anything.py,sha256=qa5r3gLJpMvP1qEeLvLSLNALBE20v7IGCRvO5Co2ge8,20507 +transformers/models/prompt_depth_anything/modular_prompt_depth_anything.py,sha256=0KZoKEkrO6JI4c9kAU2z8qnoN6FtdKuhnA-zxFjgp5o,13825 +transformers/models/prophetnet/__init__.py,sha256=TYI21JDlj449kTgKAOtUBpuxVv5L_I70CDjofSZ627M,1044 +transformers/models/prophetnet/__pycache__/__init__.cpython-310.pyc,, +transformers/models/prophetnet/__pycache__/configuration_prophetnet.cpython-310.pyc,, +transformers/models/prophetnet/__pycache__/modeling_prophetnet.cpython-310.pyc,, +transformers/models/prophetnet/__pycache__/tokenization_prophetnet.cpython-310.pyc,, +transformers/models/prophetnet/configuration_prophetnet.py,sha256=fx4EloBPW_YyczxPlDUEliAgQAejRs_0CrpscXrYng8,8943 +transformers/models/prophetnet/modeling_prophetnet.py,sha256=LjsHrJqW-IgWC_8B600N7kk3jMVlZkJ8zh6siZF3BVs,87498 +transformers/models/prophetnet/tokenization_prophetnet.py,sha256=nPUW6PS_olcfRbKhJeNpHISbX_mf1ygEayGIwSEACIs,19845 +transformers/models/pvt/__init__.py,sha256=-4ajQRrz2cTp2czAd6D23yxShatfUpHzZrHyyLRsku0,1072 +transformers/models/pvt/__pycache__/__init__.cpython-310.pyc,, +transformers/models/pvt/__pycache__/configuration_pvt.cpython-310.pyc,, +transformers/models/pvt/__pycache__/image_processing_pvt.cpython-310.pyc,, +transformers/models/pvt/__pycache__/image_processing_pvt_fast.cpython-310.pyc,, +transformers/models/pvt/__pycache__/modeling_pvt.cpython-310.pyc,, +transformers/models/pvt/configuration_pvt.py,sha256=HlD5pTeBP5WyS5zkQpRGqvcxmRyvE4EWYQ6c6tyHwyY,6362 +transformers/models/pvt/image_processing_pvt.py,sha256=AysoQbMtXEq6CcIDao37q6fYRuq3aWH4QElWMn1wXX4,13388 +transformers/models/pvt/image_processing_pvt_fast.py,sha256=dLmpkHo4M8YCjQzv3E9-b61uAkgfQAfDU-ZyZLz8UlU,1325 +transformers/models/pvt/modeling_pvt.py,sha256=I_3itQejied9CPewMa1DHyGrwMLw02P5Y04-MJCdfiQ,22525 +transformers/models/pvt_v2/__init__.py,sha256=LkmqeLd7cZGKTFX_2d9_jU0sj_bDlML042kr_vMJTLw,993 +transformers/models/pvt_v2/__pycache__/__init__.cpython-310.pyc,, +transformers/models/pvt_v2/__pycache__/configuration_pvt_v2.cpython-310.pyc,, +transformers/models/pvt_v2/__pycache__/modeling_pvt_v2.cpython-310.pyc,, +transformers/models/pvt_v2/configuration_pvt_v2.py,sha256=hF-GLYZ2NEtZl6Vy05Z7RrXXvRMFD0XBmxOgH4Dy9m8,7808 +transformers/models/pvt_v2/modeling_pvt_v2.py,sha256=Y7ff-2ZGD3cEg4fYgNDBaP8VyV1GjegtPnuwZg7NbBc,23534 +transformers/models/qwen2/__init__.py,sha256=e49oEzErXujE0UVl_q_agf5XHzHES4vV2kLwmqdk2kg,1095 +transformers/models/qwen2/__pycache__/__init__.cpython-310.pyc,, +transformers/models/qwen2/__pycache__/configuration_qwen2.cpython-310.pyc,, +transformers/models/qwen2/__pycache__/modeling_qwen2.cpython-310.pyc,, +transformers/models/qwen2/__pycache__/modular_qwen2.cpython-310.pyc,, +transformers/models/qwen2/__pycache__/tokenization_qwen2.cpython-310.pyc,, +transformers/models/qwen2/configuration_qwen2.py,sha256=fGq-jsMa5IRankvEfIOUeeboitdK8AlsY4Vv2PI4_nY,8994 +transformers/models/qwen2/modeling_qwen2.py,sha256=WoAk7vsHj5racx_8xELglhxSj0GHj9P76kuDMeHYX2Q,22663 +transformers/models/qwen2/modular_qwen2.py,sha256=wscUvUkmpZ1tH5e55cbucxp0h1g8jJ52rDcbc1IPxMI,8228 +transformers/models/qwen2/tokenization_qwen2.py,sha256=-sTmV2v-I2lzG-FHpOUw8mK98y8qxQQ2-W8Ni90vxig,3323 +transformers/models/qwen2_5_omni/__init__.py,sha256=YEDAlOoWmhkZ4L6lxmlVqVhe5A0P6aVSJNSziEFSN4E,1071 +transformers/models/qwen2_5_omni/__pycache__/__init__.cpython-310.pyc,, +transformers/models/qwen2_5_omni/__pycache__/configuration_qwen2_5_omni.cpython-310.pyc,, +transformers/models/qwen2_5_omni/__pycache__/modeling_qwen2_5_omni.cpython-310.pyc,, +transformers/models/qwen2_5_omni/__pycache__/modular_qwen2_5_omni.cpython-310.pyc,, +transformers/models/qwen2_5_omni/__pycache__/processing_qwen2_5_omni.cpython-310.pyc,, +transformers/models/qwen2_5_omni/configuration_qwen2_5_omni.py,sha256=srO94tNCjF-sz8JhEbt-88w2fPnJSafxadDScpjldmI,48048 +transformers/models/qwen2_5_omni/modeling_qwen2_5_omni.py,sha256=Q1aP7HUmqKDodjynjiOuT-RNs1OsuUZ9SnnEcF2fI6E,181312 +transformers/models/qwen2_5_omni/modular_qwen2_5_omni.py,sha256=4GA9-VC7VcJdfVxGZSw18XhPXcdzbRdtv3kFgzR4fII,186461 +transformers/models/qwen2_5_omni/processing_qwen2_5_omni.py,sha256=ZN-7KOrrUfS2j7PNAJlapotFZHVrzCYik_W5L5AtCgo,18896 +transformers/models/qwen2_5_vl/__init__.py,sha256=8-dsgLIeeE3n90n6F0XOu-tBZ-80Wotz89pjZi5GqjQ,1065 +transformers/models/qwen2_5_vl/__pycache__/__init__.cpython-310.pyc,, +transformers/models/qwen2_5_vl/__pycache__/configuration_qwen2_5_vl.cpython-310.pyc,, +transformers/models/qwen2_5_vl/__pycache__/modeling_qwen2_5_vl.cpython-310.pyc,, +transformers/models/qwen2_5_vl/__pycache__/modular_qwen2_5_vl.cpython-310.pyc,, +transformers/models/qwen2_5_vl/__pycache__/processing_qwen2_5_vl.cpython-310.pyc,, +transformers/models/qwen2_5_vl/configuration_qwen2_5_vl.py,sha256=a0iBSVqnpwDao7oT522P0jLftw63fcH7r6Zy77fkaLA,15942 +transformers/models/qwen2_5_vl/modeling_qwen2_5_vl.py,sha256=xcjnqEL_gTLTsHxiyGEqyXe1iVzKh0vQPCiqRAJOsBg,85450 +transformers/models/qwen2_5_vl/modular_qwen2_5_vl.py,sha256=JF6xSdZi3WXi12aiEyE3zA9XwdW6f0ky_Nw_OWkpwlA,42534 +transformers/models/qwen2_5_vl/processing_qwen2_5_vl.py,sha256=lEsdydHI13KkWj50EUGJHgeRDlq8Mjg4v-s5c-kgMHE,11966 +transformers/models/qwen2_audio/__init__.py,sha256=KaUmP3FK3GdeWvbunzyp1QjBki0USS4E80NlvhaJ3D8,1045 +transformers/models/qwen2_audio/__pycache__/__init__.cpython-310.pyc,, +transformers/models/qwen2_audio/__pycache__/configuration_qwen2_audio.cpython-310.pyc,, +transformers/models/qwen2_audio/__pycache__/modeling_qwen2_audio.cpython-310.pyc,, +transformers/models/qwen2_audio/__pycache__/processing_qwen2_audio.cpython-310.pyc,, +transformers/models/qwen2_audio/configuration_qwen2_audio.py,sha256=0Sv3GNIIi9Sw4wn-8cX6YyiawWIpJ1i_niHtA7uINRU,8658 +transformers/models/qwen2_audio/modeling_qwen2_audio.py,sha256=4-0BGz9jbuKae7wb5GLtDk5rj1EFYFuQxrMpaoGLRJI,39553 +transformers/models/qwen2_audio/processing_qwen2_audio.py,sha256=HNcynxm64NaFntXKua0rNVevmG9XtzaH12Ke9UH5lrc,9302 +transformers/models/qwen2_moe/__init__.py,sha256=TZM20WtUr1UyV-hDDgq5B-qFT4aUulMpjWwSUNdUs2w,999 +transformers/models/qwen2_moe/__pycache__/__init__.cpython-310.pyc,, +transformers/models/qwen2_moe/__pycache__/configuration_qwen2_moe.cpython-310.pyc,, +transformers/models/qwen2_moe/__pycache__/modeling_qwen2_moe.cpython-310.pyc,, +transformers/models/qwen2_moe/__pycache__/modular_qwen2_moe.cpython-310.pyc,, +transformers/models/qwen2_moe/configuration_qwen2_moe.py,sha256=SU6tkJBYXsAV74uiG81_ch_QUSIi-3y62AWKLL3JnWs,11609 +transformers/models/qwen2_moe/modeling_qwen2_moe.py,sha256=DdCWrlkj8GnYGP9t79CluQ8aTvdqxqvN9sWfSXB9HFI,33134 +transformers/models/qwen2_moe/modular_qwen2_moe.py,sha256=kP_NgOjiWl_Y2nJTa3X6p2ltcJddEJyxehLko1yPTkY,11147 +transformers/models/qwen2_vl/__init__.py,sha256=MtNDD6sEQws-WTLwPxUL5UNd-UyDPrDh8yWzIAsRp-U,1131 +transformers/models/qwen2_vl/__pycache__/__init__.cpython-310.pyc,, +transformers/models/qwen2_vl/__pycache__/configuration_qwen2_vl.cpython-310.pyc,, +transformers/models/qwen2_vl/__pycache__/image_processing_qwen2_vl.cpython-310.pyc,, +transformers/models/qwen2_vl/__pycache__/image_processing_qwen2_vl_fast.cpython-310.pyc,, +transformers/models/qwen2_vl/__pycache__/modeling_qwen2_vl.cpython-310.pyc,, +transformers/models/qwen2_vl/__pycache__/processing_qwen2_vl.cpython-310.pyc,, +transformers/models/qwen2_vl/__pycache__/video_processing_qwen2_vl.cpython-310.pyc,, +transformers/models/qwen2_vl/configuration_qwen2_vl.py,sha256=8I_FsnLaZPoDDOEjg-C7rrjyGnDGPbDzTKy8RM0e6Vg,14575 +transformers/models/qwen2_vl/image_processing_qwen2_vl.py,sha256=IY_5N0r2-cPDsODKidLCEwi9EEO_Zcg4bWWJAsr4hFc,24667 +transformers/models/qwen2_vl/image_processing_qwen2_vl_fast.py,sha256=eMRR6c4VYTSRkol54beN8C28aKujd_Liu0ZNesL3GqA,10537 +transformers/models/qwen2_vl/modeling_qwen2_vl.py,sha256=u2PCmqUk1y6RmEoFdTVgrfds444GCHHan2EDOKsawdU,79735 +transformers/models/qwen2_vl/processing_qwen2_vl.py,sha256=lZadXj-j7mdK7Hq18iwz2pkAhQxOGx2aAm1v0LkNMTw,9774 +transformers/models/qwen2_vl/video_processing_qwen2_vl.py,sha256=q-40Qr6MsTnwIdKOmlFUXE_xVkh1o3PGfkaQ5xmkgmo,14498 +transformers/models/qwen3/__init__.py,sha256=5JU8uO9x0AmJ-YjY36MxtbMKT_B38dLJkrnAwLyjcTY,1014 +transformers/models/qwen3/__pycache__/__init__.cpython-310.pyc,, +transformers/models/qwen3/__pycache__/configuration_qwen3.cpython-310.pyc,, +transformers/models/qwen3/__pycache__/modeling_qwen3.cpython-310.pyc,, +transformers/models/qwen3/__pycache__/modular_qwen3.cpython-310.pyc,, +transformers/models/qwen3/configuration_qwen3.py,sha256=Tu8HtqXQj7VGR0pSj5HRgRhQjBaMINsL0pS3qzMJlb8,9577 +transformers/models/qwen3/modeling_qwen3.py,sha256=eX-GARYlsglHU2J-k6k2kHG7ZUbyZUfaibt4yaDsozg,24094 +transformers/models/qwen3/modular_qwen3.py,sha256=EgFgo1qFvjdPERJTZI5w1V_AKWUuW_eT4TsGKCcwSBc,5965 +transformers/models/qwen3_5/__init__.py,sha256=4da9M8C_zn94Li0Yb4S8wOQvgmDqyFwQ0Wu3gIZlobU,1035 +transformers/models/qwen3_5/__pycache__/__init__.cpython-310.pyc,, +transformers/models/qwen3_5/__pycache__/configuration_qwen3_5.cpython-310.pyc,, +transformers/models/qwen3_5/__pycache__/modeling_qwen3_5.cpython-310.pyc,, +transformers/models/qwen3_5/__pycache__/modular_qwen3_5.cpython-310.pyc,, +transformers/models/qwen3_5/__pycache__/tokenization_qwen3_5.cpython-310.pyc,, +transformers/models/qwen3_5/configuration_qwen3_5.py,sha256=LsEy5exWENPIEQxl7XHLT0nJjEnxt56tDslzzblJ3WE,14718 +transformers/models/qwen3_5/modeling_qwen3_5.py,sha256=DnQQ9SUeXDJKVijFNA7jVR96alBc45hWn8w7XzrAf3o,101574 +transformers/models/qwen3_5/modular_qwen3_5.py,sha256=uH-uRrFdrTXg2pva98KH_omQwWdGbVIwnSe_wk1z9vc,33776 +transformers/models/qwen3_5/tokenization_qwen3_5.py,sha256=PS-Yq8HG7sYeRUgXEoa4j16Bc6xtY5VLj9Ilt-JM8lo,3127 +transformers/models/qwen3_5_moe/__init__.py,sha256=u611HCFpy5zFLNE9U0Ae0BcaT5gOja1Iw_b7M57Ksw0,1003 +transformers/models/qwen3_5_moe/__pycache__/__init__.cpython-310.pyc,, +transformers/models/qwen3_5_moe/__pycache__/configuration_qwen3_5_moe.cpython-310.pyc,, +transformers/models/qwen3_5_moe/__pycache__/modeling_qwen3_5_moe.cpython-310.pyc,, +transformers/models/qwen3_5_moe/__pycache__/modular_qwen3_5_moe.cpython-310.pyc,, +transformers/models/qwen3_5_moe/configuration_qwen3_5_moe.py,sha256=jZAZxsKQS8ZJWFYj0V2sUhkyIZfdYl_jwj4K2av1y84,16265 +transformers/models/qwen3_5_moe/modeling_qwen3_5_moe.py,sha256=EJakUHPa0BX1IahokNSR0aTGVee5inpWE5ST-m7fOsQ,112022 +transformers/models/qwen3_5_moe/modular_qwen3_5_moe.py,sha256=kAj9vDmyIXB9-sY8VfRkvQ5uVFveUdLuzYdGExut4OA,19428 +transformers/models/qwen3_moe/__init__.py,sha256=q5WfIniJecmOju3Lhy277H3Puu7viwc9vUhUWen3UZY,999 +transformers/models/qwen3_moe/__pycache__/__init__.cpython-310.pyc,, +transformers/models/qwen3_moe/__pycache__/configuration_qwen3_moe.cpython-310.pyc,, +transformers/models/qwen3_moe/__pycache__/modeling_qwen3_moe.cpython-310.pyc,, +transformers/models/qwen3_moe/__pycache__/modular_qwen3_moe.cpython-310.pyc,, +transformers/models/qwen3_moe/configuration_qwen3_moe.py,sha256=yoOL-MkJ8_Foa3Ykh_SAKk8-l-A7DsXHZCfi-asp-2c,10771 +transformers/models/qwen3_moe/modeling_qwen3_moe.py,sha256=LGXcvG2U22WG1WZkS2s7NsbdgFlZUiiYdRTw1WJeQAY,32605 +transformers/models/qwen3_moe/modular_qwen3_moe.py,sha256=ps6IJBxroHwVqBClJx70vozfErWrllo5-EuKD1Naz1o,7377 +transformers/models/qwen3_next/__init__.py,sha256=PuPvF5xcEfBxUKjqiZaWCiHeDeKuTmNdfuI6wvb-cbI,1001 +transformers/models/qwen3_next/__pycache__/__init__.cpython-310.pyc,, +transformers/models/qwen3_next/__pycache__/configuration_qwen3_next.cpython-310.pyc,, +transformers/models/qwen3_next/__pycache__/modeling_qwen3_next.cpython-310.pyc,, +transformers/models/qwen3_next/__pycache__/modular_qwen3_next.cpython-310.pyc,, +transformers/models/qwen3_next/configuration_qwen3_next.py,sha256=NVDoFIZvfmp2uomU1YX-3JFo60NvD1yRp6p3wD4h42Y,12609 +transformers/models/qwen3_next/modeling_qwen3_next.py,sha256=PS2nYkcua5BM7xKQ1MoDsVpjFvkmn2ykL5G9YOuRAzc,56870 +transformers/models/qwen3_next/modular_qwen3_next.py,sha256=JrYP_R2yx9UBJJAY9rUMohrx6GzNgZYb0NbCS5_TKnc,38412 +transformers/models/qwen3_omni_moe/__init__.py,sha256=6xE3okskjamaUt4t3k8qJeJWbTPvLH7MfEjmtKtCC3I,1077 +transformers/models/qwen3_omni_moe/__pycache__/__init__.cpython-310.pyc,, +transformers/models/qwen3_omni_moe/__pycache__/configuration_qwen3_omni_moe.cpython-310.pyc,, +transformers/models/qwen3_omni_moe/__pycache__/modeling_qwen3_omni_moe.cpython-310.pyc,, +transformers/models/qwen3_omni_moe/__pycache__/modular_qwen3_omni_moe.cpython-310.pyc,, +transformers/models/qwen3_omni_moe/__pycache__/processing_qwen3_omni_moe.cpython-310.pyc,, +transformers/models/qwen3_omni_moe/configuration_qwen3_omni_moe.py,sha256=658iXXl2ki5lAJzgSHnkT-Besr6kzkKO53ySJoiC2-Q,58487 +transformers/models/qwen3_omni_moe/modeling_qwen3_omni_moe.py,sha256=hgy2OUd1ZMh3Dq0yEZdRXGyOiumSScSYOrezJd-avsQ,183384 +transformers/models/qwen3_omni_moe/modular_qwen3_omni_moe.py,sha256=SXJc0FN2f6y0oYXTiFlqyNFmL47q4mSHMyGYsH9INXE,131638 +transformers/models/qwen3_omni_moe/processing_qwen3_omni_moe.py,sha256=rjbWUIMcVVsNL3UbCqa1jurJ0YCehfxiPExHQ4LHr0c,19063 +transformers/models/qwen3_vl/__init__.py,sha256=abVaeHwwKgL-3gVI3c5PSZfroZlU4TxEKXweDd75BXQ,1104 +transformers/models/qwen3_vl/__pycache__/__init__.cpython-310.pyc,, +transformers/models/qwen3_vl/__pycache__/configuration_qwen3_vl.cpython-310.pyc,, +transformers/models/qwen3_vl/__pycache__/modeling_qwen3_vl.cpython-310.pyc,, +transformers/models/qwen3_vl/__pycache__/modular_qwen3_vl.cpython-310.pyc,, +transformers/models/qwen3_vl/__pycache__/processing_qwen3_vl.cpython-310.pyc,, +transformers/models/qwen3_vl/__pycache__/video_processing_qwen3_vl.cpython-310.pyc,, +transformers/models/qwen3_vl/configuration_qwen3_vl.py,sha256=jDvWjnIV8COEnVucJnIK2pRroXlcHiKp8xnzPjnVtEM,12369 +transformers/models/qwen3_vl/modeling_qwen3_vl.py,sha256=7zlO5tKSI6-W1QKs-w8BkcFHIazSQyptmGHvnvfn-pE,80645 +transformers/models/qwen3_vl/modular_qwen3_vl.py,sha256=OptjYF0QXzyX1tBclFg9UIk4EGkMTZaidRktEsI-tUA,62857 +transformers/models/qwen3_vl/processing_qwen3_vl.py,sha256=5au68dA1_knNg1Tx6S_T-SqxEDo5FzwUdHHzD_GQi2o,13938 +transformers/models/qwen3_vl/video_processing_qwen3_vl.py,sha256=oy8h1ZpPNj3PJFFqW1_DtnY8j_k7A6_OQ1-upVhiPhA,11289 +transformers/models/qwen3_vl_moe/__init__.py,sha256=kZX59YLK-ZPItl-fKkUko_3uNM_QthuwE-rfzurn9iY,1028 +transformers/models/qwen3_vl_moe/__pycache__/__init__.cpython-310.pyc,, +transformers/models/qwen3_vl_moe/__pycache__/configuration_qwen3_vl_moe.cpython-310.pyc,, +transformers/models/qwen3_vl_moe/__pycache__/modeling_qwen3_vl_moe.cpython-310.pyc,, +transformers/models/qwen3_vl_moe/__pycache__/modular_qwen3_vl_moe.cpython-310.pyc,, +transformers/models/qwen3_vl_moe/configuration_qwen3_vl_moe.py,sha256=O8zBJf9DtTP3LtOn5kH65DGN8Lgn1MhfVd4gu-TbXm4,14433 +transformers/models/qwen3_vl_moe/modeling_qwen3_vl_moe.py,sha256=cmJ0ShEYeQT9Eyd5Zm2isDg4Sg3FMVlkO7lm0_-bZro,90377 +transformers/models/qwen3_vl_moe/modular_qwen3_vl_moe.py,sha256=jhLCqNVVQOAQc7e-3HocHEnWV3e7mPvL3ET4J_6qyUc,25331 +transformers/models/rag/__init__.py,sha256=IRUxwdcZdE-6fRnJUhqgl8bB_Iu2XaHUa2qDvdK8zMQ,1056 +transformers/models/rag/__pycache__/__init__.cpython-310.pyc,, +transformers/models/rag/__pycache__/configuration_rag.cpython-310.pyc,, +transformers/models/rag/__pycache__/modeling_rag.cpython-310.pyc,, +transformers/models/rag/__pycache__/retrieval_rag.cpython-310.pyc,, +transformers/models/rag/__pycache__/tokenization_rag.cpython-310.pyc,, +transformers/models/rag/configuration_rag.py,sha256=MORbrWKZlOSld-y3j2K8BetHRmMbJx64SgiChachptQ,8104 +transformers/models/rag/modeling_rag.py,sha256=eR09aN4OFlJROgDw9HP3rNaTMG1psbYnPVKbB9bD1S0,88529 +transformers/models/rag/retrieval_rag.py,sha256=xp-ymlC7bEVcEF5qx6KSpcaadliHxFNhqQptTs81lfk,29948 +transformers/models/rag/tokenization_rag.py,sha256=tboHOP0AiAEM2O6S4Cjs-mGRn54z29D9ijWCGLXqF6E,2784 +transformers/models/recurrent_gemma/__init__.py,sha256=i86Cydx-eAdwsVMjNc0yG9hGxe_amyfAdvF5Eg-UCGM,1011 +transformers/models/recurrent_gemma/__pycache__/__init__.cpython-310.pyc,, +transformers/models/recurrent_gemma/__pycache__/configuration_recurrent_gemma.cpython-310.pyc,, +transformers/models/recurrent_gemma/__pycache__/modeling_recurrent_gemma.cpython-310.pyc,, +transformers/models/recurrent_gemma/configuration_recurrent_gemma.py,sha256=lnDTGz6x_8MY-SyaD7nK4zW6vJ4bNxvafCPWse8C0Vc,8391 +transformers/models/recurrent_gemma/modeling_recurrent_gemma.py,sha256=b23vw6BpOdHd1N2UIsOn6tIXo8ztRnSw9eGbsv9b6tc,38538 +transformers/models/reformer/__init__.py,sha256=hJ-mLQGtig9HdVaq2HBnpc5qAhWb4OBfjdidb55QBrY,1038 +transformers/models/reformer/__pycache__/__init__.cpython-310.pyc,, +transformers/models/reformer/__pycache__/configuration_reformer.cpython-310.pyc,, +transformers/models/reformer/__pycache__/modeling_reformer.cpython-310.pyc,, +transformers/models/reformer/__pycache__/tokenization_reformer.cpython-310.pyc,, +transformers/models/reformer/configuration_reformer.py,sha256=Uybcqdvz1JswZttlMa15U0DhD_1GnuiZAJl2ddPDz-8,13234 +transformers/models/reformer/modeling_reformer.py,sha256=5Row18RxM4dIfXOZQLsBqV0uSMtYpfuj6omJwqWFUPA,113364 +transformers/models/reformer/tokenization_reformer.py,sha256=S-OLmGyWWs1rHVNnak0RBjE8v2_Q5ogvN0ZL5NGgIaQ,4326 +transformers/models/regnet/__init__.py,sha256=ycvH_P4FO9zOsxgrXAXAHtK7FXQCjUJz6EgwLH4JD9c,993 +transformers/models/regnet/__pycache__/__init__.cpython-310.pyc,, +transformers/models/regnet/__pycache__/configuration_regnet.cpython-310.pyc,, +transformers/models/regnet/__pycache__/modeling_regnet.cpython-310.pyc,, +transformers/models/regnet/configuration_regnet.py,sha256=AEk3PMRU_EsDVRiZLybS7tz9ZIrmAxqAifDSl4Z45fk,3959 +transformers/models/regnet/modeling_regnet.py,sha256=mE8VfiUOeMNhEbAKvNMPyIjT3Xwi2j3fiZxt7Ps-Fg0,14335 +transformers/models/rembert/__init__.py,sha256=2-jjTgRWHbTKw873X9XGzooYrv9BlSSIvz7GcemXGbw,1035 +transformers/models/rembert/__pycache__/__init__.cpython-310.pyc,, +transformers/models/rembert/__pycache__/configuration_rembert.cpython-310.pyc,, +transformers/models/rembert/__pycache__/modeling_rembert.cpython-310.pyc,, +transformers/models/rembert/__pycache__/tokenization_rembert.cpython-310.pyc,, +transformers/models/rembert/configuration_rembert.py,sha256=AWGlY2ppaWHmgRqWAMbNBwiHsqaSwh6NEPn3k2sohys,6731 +transformers/models/rembert/modeling_rembert.py,sha256=om5B6FnfDBYwy3VN4IqaUxRQY7Hx0QaD7I92X5hlM0I,49164 +transformers/models/rembert/tokenization_rembert.py,sha256=KvTdia7SYOJ2yaOueM2y7oQdF3BSkD_SXTambhzVYb4,7808 +transformers/models/resnet/__init__.py,sha256=fvRmAOL_0o36oByTYgw9MmHL4wB20CHQ7h68S5fDazs,993 +transformers/models/resnet/__pycache__/__init__.cpython-310.pyc,, +transformers/models/resnet/__pycache__/configuration_resnet.cpython-310.pyc,, +transformers/models/resnet/__pycache__/modeling_resnet.cpython-310.pyc,, +transformers/models/resnet/configuration_resnet.py,sha256=8GTNIode9_TMXVIOuvi4XRtv2dRUsHLUOs22JRJP6w8,5359 +transformers/models/resnet/modeling_resnet.py,sha256=VF54FvzljMw4Q6l2TdaFvRBvD8Zc3UCDjgaCLai0gX4,16569 +transformers/models/roberta/__init__.py,sha256=L5plEsZ85q9ufY9TKiQoW0V0xzGOJ12WVI2dFHicq-k,1035 +transformers/models/roberta/__pycache__/__init__.cpython-310.pyc,, +transformers/models/roberta/__pycache__/configuration_roberta.cpython-310.pyc,, +transformers/models/roberta/__pycache__/modeling_roberta.cpython-310.pyc,, +transformers/models/roberta/__pycache__/modular_roberta.cpython-310.pyc,, +transformers/models/roberta/__pycache__/tokenization_roberta.cpython-310.pyc,, +transformers/models/roberta/__pycache__/tokenization_roberta_old.cpython-310.pyc,, +transformers/models/roberta/configuration_roberta.py,sha256=QS8iP1mb17wSv3mBvqbmQ7tVaBqcmbcsJgi4Wd-lU-4,6196 +transformers/models/roberta/modeling_roberta.py,sha256=_og5zyUgzoXNOWPN0DNKOiUSEBOisFFsQiw-cEyWj2w,54685 +transformers/models/roberta/modular_roberta.py,sha256=A-7fLxwAkh8At_lTN7exZR56ujRJm6D6MnMm9Y5MHSk,31676 +transformers/models/roberta/tokenization_roberta.py,sha256=Y5CLVBJtUu7rSugjxvMsSb3B48GkPALEt0fjh1UW-aE,7378 +transformers/models/roberta/tokenization_roberta_old.py,sha256=0-oEwTRx5FxsyVcHmVeofxJpmzNU8qCJTKgwl23uMMg,10935 +transformers/models/roberta_prelayernorm/__init__.py,sha256=oZ3DNaebEY7KXvSEjkOGdDGHzqbtrqk0efDZ-sM3W2k,1021 +transformers/models/roberta_prelayernorm/__pycache__/__init__.cpython-310.pyc,, +transformers/models/roberta_prelayernorm/__pycache__/configuration_roberta_prelayernorm.cpython-310.pyc,, +transformers/models/roberta_prelayernorm/__pycache__/modeling_roberta_prelayernorm.cpython-310.pyc,, +transformers/models/roberta_prelayernorm/configuration_roberta_prelayernorm.py,sha256=Mu6vMqvfsrkzkVVQRhg1jvGY9cL8XP_84J_7iADO-Es,6592 +transformers/models/roberta_prelayernorm/modeling_roberta_prelayernorm.py,sha256=kC81nzYjYyhvc4l_tm_9pUK6vaIYpQb1FYsqzof3Dc8,58397 +transformers/models/roc_bert/__init__.py,sha256=4CveMGU-dY3nV4E6x-Xpb1jicRniwrPuSOrY8-SHIUI,1038 +transformers/models/roc_bert/__pycache__/__init__.cpython-310.pyc,, +transformers/models/roc_bert/__pycache__/configuration_roc_bert.cpython-310.pyc,, +transformers/models/roc_bert/__pycache__/modeling_roc_bert.cpython-310.pyc,, +transformers/models/roc_bert/__pycache__/tokenization_roc_bert.cpython-310.pyc,, +transformers/models/roc_bert/configuration_roc_bert.py,sha256=4S8CwXCuZf2OKPBqBbRXTW6T2L7Hr0wOm-kUlnDL1d0,8020 +transformers/models/roc_bert/modeling_roc_bert.py,sha256=PJPpZZ81w-fMQKsYtNyh0xiBychRWV9seN9el0gqXKo,74653 +transformers/models/roc_bert/tokenization_roc_bert.py,sha256=HGUL8avso6HH4kiyVYhQ33L2f2k2_2Pmggi0-f4G1sk,58670 +transformers/models/roformer/__init__.py,sha256=ujlqcOUcpfg7P3ICGkMw00Dv8Z7wldj-8ctGf8zmk4A,1084 +transformers/models/roformer/__pycache__/__init__.cpython-310.pyc,, +transformers/models/roformer/__pycache__/configuration_roformer.cpython-310.pyc,, +transformers/models/roformer/__pycache__/modeling_roformer.cpython-310.pyc,, +transformers/models/roformer/__pycache__/tokenization_roformer.cpython-310.pyc,, +transformers/models/roformer/__pycache__/tokenization_utils.cpython-310.pyc,, +transformers/models/roformer/configuration_roformer.py,sha256=tpWq5-eL-Zx0rf1foHH9VLbbHWM9FmHXhUN1FrMAKIw,6517 +transformers/models/roformer/modeling_roformer.py,sha256=-qtEaFM3AKMverCrFmkcxeSoW97AvK3Et3lDYnSwglM,56671 +transformers/models/roformer/tokenization_roformer.py,sha256=OP7Z4HNkVPShy7llQuwDHfqyZTGshBo0IhwGZPlgyr8,6246 +transformers/models/roformer/tokenization_utils.py,sha256=n5oqaXLHh85OA7sRbcQ9VBYxQEV4Syy8l72Hy7gz0aU,2610 +transformers/models/rt_detr/__init__.py,sha256=c9Y3NeKQwBP46tyFF99kjqTngoIWhLMq7XvzEJOfLaY,1181 +transformers/models/rt_detr/__pycache__/__init__.cpython-310.pyc,, +transformers/models/rt_detr/__pycache__/configuration_rt_detr.cpython-310.pyc,, +transformers/models/rt_detr/__pycache__/configuration_rt_detr_resnet.cpython-310.pyc,, +transformers/models/rt_detr/__pycache__/image_processing_rt_detr.cpython-310.pyc,, +transformers/models/rt_detr/__pycache__/image_processing_rt_detr_fast.cpython-310.pyc,, +transformers/models/rt_detr/__pycache__/modeling_rt_detr.cpython-310.pyc,, +transformers/models/rt_detr/__pycache__/modeling_rt_detr_resnet.cpython-310.pyc,, +transformers/models/rt_detr/__pycache__/modular_rt_detr.cpython-310.pyc,, +transformers/models/rt_detr/configuration_rt_detr.py,sha256=b66skTfWTj4HehMeQ7veT-MBpNhQnNA4cKKgJ-6w8jU,15071 +transformers/models/rt_detr/configuration_rt_detr_resnet.py,sha256=UWqeor5AVhUMR0F9uiZHfazsQ6fanG7nh0cNOD9KYrs,5397 +transformers/models/rt_detr/image_processing_rt_detr.py,sha256=rmuOPoU1ZwW1vChsXq6GddJCaCFkba3t238axnmViVA,49676 +transformers/models/rt_detr/image_processing_rt_detr_fast.py,sha256=k1zDPKROmDwThyVbcvBjsoJbiVutPIll8u2Mu51uuUI,23047 +transformers/models/rt_detr/modeling_rt_detr.py,sha256=EarzFBgTmIsGp1Dmpyrtb4i1WOgpm7as96smB320OHE,84593 +transformers/models/rt_detr/modeling_rt_detr_resnet.py,sha256=sNRvE5Q7IzLGRFA6RIh7zqmNu0NPdoU4J6z-o0lNPFs,15487 +transformers/models/rt_detr/modular_rt_detr.py,sha256=V9hFzwh5xQpATNPqupOJsPEK6p9ZwDpZglUQREq345k,84112 +transformers/models/rt_detr_v2/__init__.py,sha256=7RL5U-hsGt3HQZ5SuWn8iZY_L166EYswBvaQXFRkzRc,1003 +transformers/models/rt_detr_v2/__pycache__/__init__.cpython-310.pyc,, +transformers/models/rt_detr_v2/__pycache__/configuration_rt_detr_v2.cpython-310.pyc,, +transformers/models/rt_detr_v2/__pycache__/modeling_rt_detr_v2.cpython-310.pyc,, +transformers/models/rt_detr_v2/__pycache__/modular_rt_detr_v2.cpython-310.pyc,, +transformers/models/rt_detr_v2/configuration_rt_detr_v2.py,sha256=le_3yRe5CS4H9V2LASKq2STQj2QpYIDKL80lA9BIa-w,16657 +transformers/models/rt_detr_v2/modeling_rt_detr_v2.py,sha256=Y0fd_wxA7e5wBTCwE0To94O1SHxba-ANCJhK8ak9E9E,86678 +transformers/models/rt_detr_v2/modular_rt_detr_v2.py,sha256=UY30z2zFrKtFJ8LZXvyJuh_u-EL3m61STHhygQ_tsMk,27165 +transformers/models/rwkv/__init__.py,sha256=HAiwEvW1j_xuHj_PbmN25srY9RtA1gLmN_0RWvAyG78,989 +transformers/models/rwkv/__pycache__/__init__.cpython-310.pyc,, +transformers/models/rwkv/__pycache__/configuration_rwkv.cpython-310.pyc,, +transformers/models/rwkv/__pycache__/modeling_rwkv.cpython-310.pyc,, +transformers/models/rwkv/configuration_rwkv.py,sha256=oCueGonvMH-ECnQZQu-8GbAymz_UQx_eXnQ6eu0yOsQ,5127 +transformers/models/rwkv/modeling_rwkv.py,sha256=vD1zAx8kHirX-c0hQubEqpgJa8C0NER9E1DoFoBtN_o,32129 +transformers/models/sam/__init__.py,sha256=piwSVkUVVyFvPUuusA3QYxDGIwYo9KmztKxhwJ8oVCM,1106 +transformers/models/sam/__pycache__/__init__.cpython-310.pyc,, +transformers/models/sam/__pycache__/configuration_sam.cpython-310.pyc,, +transformers/models/sam/__pycache__/image_processing_sam.cpython-310.pyc,, +transformers/models/sam/__pycache__/image_processing_sam_fast.cpython-310.pyc,, +transformers/models/sam/__pycache__/modeling_sam.cpython-310.pyc,, +transformers/models/sam/__pycache__/processing_sam.cpython-310.pyc,, +transformers/models/sam/configuration_sam.py,sha256=wVQstISbdgjAjTBGZC6LeZqCJSBOJB-4EnrfJq__AHU,14833 +transformers/models/sam/image_processing_sam.py,sha256=ikmW7oIAg1W0iYXeyNulwnrKYNor7xXQLde-kD5Am8Y,54438 +transformers/models/sam/image_processing_sam_fast.py,sha256=cePFZ-aS3d_TnAbrSxv4Lp7KYqKkNtjysZV-OEJ8D4U,33122 +transformers/models/sam/modeling_sam.py,sha256=AxHdyt9zC2dwEfMorgmcCOsfON6-K5sdIMB5NWJtlqg,61321 +transformers/models/sam/processing_sam.py,sha256=hH49ghIKhju1NnWo0aq32kzktpUvcBu_5BA6_6oqMh4,12559 +transformers/models/sam2/__init__.py,sha256=H7LrRCnUmUZ9fj5C_p_Mp8xNB5Zdtoo1S__LcYcs_i4,1070 +transformers/models/sam2/__pycache__/__init__.cpython-310.pyc,, +transformers/models/sam2/__pycache__/configuration_sam2.cpython-310.pyc,, +transformers/models/sam2/__pycache__/image_processing_sam2_fast.cpython-310.pyc,, +transformers/models/sam2/__pycache__/modeling_sam2.cpython-310.pyc,, +transformers/models/sam2/__pycache__/modular_sam2.cpython-310.pyc,, +transformers/models/sam2/__pycache__/processing_sam2.cpython-310.pyc,, +transformers/models/sam2/configuration_sam2.py,sha256=Zq2JvDJnTsn22P1Za_ZfOSPkmqYfSMs7yY4uplwjpWw,20937 +transformers/models/sam2/image_processing_sam2_fast.py,sha256=9hSRtetQTGa0vF2mdYwcxqKylnBZq-23nrn2xLzpwh0,30440 +transformers/models/sam2/modeling_sam2.py,sha256=zkUGQ5NgA4kbt8BEB4lD9aIb6cEpuvF1gSa6uaTPrpk,72391 +transformers/models/sam2/modular_sam2.py,sha256=4Zix1mYXn6ZenS5-h6J6SnrSvz54b2epWC0rqQu5nBY,64708 +transformers/models/sam2/processing_sam2.py,sha256=3B53-zcWIYe6X19WZDxx2-HQuJxEHJSXdmzUZjX35hs,22411 +transformers/models/sam2_video/__init__.py,sha256=WFP70wbKsoPQuuR0Aq6sMpFZ9m2cQJwNgdCpngg4C1o,1089 +transformers/models/sam2_video/__pycache__/__init__.cpython-310.pyc,, +transformers/models/sam2_video/__pycache__/configuration_sam2_video.cpython-310.pyc,, +transformers/models/sam2_video/__pycache__/modeling_sam2_video.cpython-310.pyc,, +transformers/models/sam2_video/__pycache__/modular_sam2_video.cpython-310.pyc,, +transformers/models/sam2_video/__pycache__/processing_sam2_video.cpython-310.pyc,, +transformers/models/sam2_video/__pycache__/video_processing_sam2_video.cpython-310.pyc,, +transformers/models/sam2_video/configuration_sam2_video.py,sha256=-RbxxjiFG64YWo2WVU86QkGm4PjZNtr5-MQGo-u_6N4,20735 +transformers/models/sam2_video/modeling_sam2_video.py,sha256=fe46o-EGp7AMHwhES-YllecDKy1nyIPJbRrbQtvPx0g,133217 +transformers/models/sam2_video/modular_sam2_video.py,sha256=pThB_DqbK9jo1pres2lXfwM5l6k7urlDdbQERXFgfa4,124707 +transformers/models/sam2_video/processing_sam2_video.py,sha256=87Qw8x3OL9lhAKAz85q4RhbipVuZfSBzKQokDpZJzXQ,37447 +transformers/models/sam2_video/video_processing_sam2_video.py,sha256=TZt4Yd149iJBA2wXH8IqkxHEATRZJAom5bE2UxY-0MQ,4868 +transformers/models/sam3/__init__.py,sha256=sHbyLDFgub6Y90Saw8bbz2UQhMDMMTgg8Ko7FbhsZuQ,1024 +transformers/models/sam3/__pycache__/__init__.cpython-310.pyc,, +transformers/models/sam3/__pycache__/configuration_sam3.cpython-310.pyc,, +transformers/models/sam3/__pycache__/image_processing_sam3_fast.cpython-310.pyc,, +transformers/models/sam3/__pycache__/modeling_sam3.cpython-310.pyc,, +transformers/models/sam3/__pycache__/modular_sam3.cpython-310.pyc,, +transformers/models/sam3/__pycache__/processing_sam3.cpython-310.pyc,, +transformers/models/sam3/configuration_sam3.py,sha256=2ocwbfmnQlMWkS9jzbiOD7KcWB-Qp4C8AzChGwMUHNc,21262 +transformers/models/sam3/image_processing_sam3_fast.py,sha256=LghEP1DwcgGe-8l2HuRKw3nKST-04gPeQ7yei3a9Jf4,40707 +transformers/models/sam3/modeling_sam3.py,sha256=yuIK9LRpBQ45HkIbHTBHEX_kpOtEfCcqPT7pMm0vm5s,101596 +transformers/models/sam3/modular_sam3.py,sha256=Yg-pc7YbE7MYhJMVx8LtjkaqIGtR7cJnCTX_Kte2zb8,11324 +transformers/models/sam3/processing_sam3.py,sha256=bt2IvjgXKdN_1tTr7Wq8hNDzMn8NIQjD_bFGtPE199Q,27873 +transformers/models/sam3_tracker/__init__.py,sha256=TPRKgIS2Z6Wq8WTVACG7_2akZcTNqFNnBYeDOjZF2Aw,1049 +transformers/models/sam3_tracker/__pycache__/__init__.cpython-310.pyc,, +transformers/models/sam3_tracker/__pycache__/configuration_sam3_tracker.cpython-310.pyc,, +transformers/models/sam3_tracker/__pycache__/modeling_sam3_tracker.cpython-310.pyc,, +transformers/models/sam3_tracker/__pycache__/modular_sam3_tracker.cpython-310.pyc,, +transformers/models/sam3_tracker/__pycache__/processing_sam3_tracker.cpython-310.pyc,, +transformers/models/sam3_tracker/configuration_sam3_tracker.py,sha256=4wz8a8vXFRbt70loH1Fn0Vhg1Flw9tzaQCVtSDt4PFQ,11637 +transformers/models/sam3_tracker/modeling_sam3_tracker.py,sha256=SEdJkRelna_VqnyBTLMWZnswkzj0YBbeZVXpAkc0Zic,53767 +transformers/models/sam3_tracker/modular_sam3_tracker.py,sha256=TBR0p2VHKQbBKQo_CNQIyq1mYlcEMM712HBuT2eXZKk,10998 +transformers/models/sam3_tracker/processing_sam3_tracker.py,sha256=Q9uNPR1hyuQiiH4Axssmxyxhgzg6v8RGucQrD-wzZ7U,23143 +transformers/models/sam3_tracker_video/__init__.py,sha256=WEogj5NnwI_O925jgVstv_dAiSqHq1pPTmkWWxGzOiY,1067 +transformers/models/sam3_tracker_video/__pycache__/__init__.cpython-310.pyc,, +transformers/models/sam3_tracker_video/__pycache__/configuration_sam3_tracker_video.cpython-310.pyc,, +transformers/models/sam3_tracker_video/__pycache__/modeling_sam3_tracker_video.cpython-310.pyc,, +transformers/models/sam3_tracker_video/__pycache__/modular_sam3_tracker_video.cpython-310.pyc,, +transformers/models/sam3_tracker_video/__pycache__/processing_sam3_tracker_video.cpython-310.pyc,, +transformers/models/sam3_tracker_video/configuration_sam3_tracker_video.py,sha256=BCdBzwn4DehMjzx9P83IBUmeRLa9AgALbe2oFm3VgzA,22170 +transformers/models/sam3_tracker_video/modeling_sam3_tracker_video.py,sha256=FpYkkmaciwBAqOzeUabkrkmWlg9QEeX8q4lNYt_Mbr0,134988 +transformers/models/sam3_tracker_video/modular_sam3_tracker_video.py,sha256=aXScrGYdOPdjKtnKYN13nru7scHfKSeQxZHSOwzb9xg,26543 +transformers/models/sam3_tracker_video/processing_sam3_tracker_video.py,sha256=4JC7q7aXLBr1kUdhPiAbVvxyR7Hs-oEm5dJ-9KDmaOo,37541 +transformers/models/sam3_video/__init__.py,sha256=-FBW7aAvRRXbmSCE0NRCcjbgaStvq1lgOn4h8-7ZbGE,1042 +transformers/models/sam3_video/__pycache__/__init__.cpython-310.pyc,, +transformers/models/sam3_video/__pycache__/configuration_sam3_video.cpython-310.pyc,, +transformers/models/sam3_video/__pycache__/modeling_sam3_video.cpython-310.pyc,, +transformers/models/sam3_video/__pycache__/processing_sam3_video.cpython-310.pyc,, +transformers/models/sam3_video/configuration_sam3_video.py,sha256=ossxhnLIUK6Iq5081wdtVssaKPhuAQjBgtQp1e_jDDI,12013 +transformers/models/sam3_video/modeling_sam3_video.py,sha256=0OiFw75ccDM2jofEXnRDwhFo4w7PPCJjkRPIcx8N22Y,92980 +transformers/models/sam3_video/processing_sam3_video.py,sha256=a_2l-7dBOGi0K7HD28AxC3FmGlUax8hY3xTnpxkvHsM,17653 +transformers/models/sam_hq/__init__.py,sha256=4B3IBWfFKvM9GThbmIj6Ig-KAUbOquWgv0RW3QvNjxM,1030 +transformers/models/sam_hq/__pycache__/__init__.cpython-310.pyc,, +transformers/models/sam_hq/__pycache__/configuration_sam_hq.cpython-310.pyc,, +transformers/models/sam_hq/__pycache__/modeling_sam_hq.cpython-310.pyc,, +transformers/models/sam_hq/__pycache__/modular_sam_hq.cpython-310.pyc,, +transformers/models/sam_hq/__pycache__/processing_sam_hq.cpython-310.pyc,, +transformers/models/sam_hq/configuration_sam_hq.py,sha256=W-pQEY4muyeJgRBApcRH-IGcYZuIrUrnRBSTfJkjiIM,14957 +transformers/models/sam_hq/modeling_sam_hq.py,sha256=0_pjsOZmC3EdUDFxV0S-JM03p0m2AQgN5NEJOpESASI,68936 +transformers/models/sam_hq/modular_sam_hq.py,sha256=Ayc0B4IkYlqBisDkLL6lb4Isf7nKN52Tjn9oBWvOzXw,31411 +transformers/models/sam_hq/processing_sam_hq.py,sha256=d3HkKI9FLzK7w9BIbXXU7-v6bRrcJuJb1c1kBSthARs,13391 +transformers/models/seamless_m4t/__init__.py,sha256=aGTGuFUq4FqWWVcwKaf0ehT4bQpECvqA5V0Tcrm1WtY,1144 +transformers/models/seamless_m4t/__pycache__/__init__.cpython-310.pyc,, +transformers/models/seamless_m4t/__pycache__/configuration_seamless_m4t.cpython-310.pyc,, +transformers/models/seamless_m4t/__pycache__/feature_extraction_seamless_m4t.cpython-310.pyc,, +transformers/models/seamless_m4t/__pycache__/modeling_seamless_m4t.cpython-310.pyc,, +transformers/models/seamless_m4t/__pycache__/processing_seamless_m4t.cpython-310.pyc,, +transformers/models/seamless_m4t/__pycache__/tokenization_seamless_m4t.cpython-310.pyc,, +transformers/models/seamless_m4t/configuration_seamless_m4t.py,sha256=cdziRk7bVWYtLRK_AQsXE9uvAvMhKMSO0Wc_EXkjBEo,23570 +transformers/models/seamless_m4t/feature_extraction_seamless_m4t.py,sha256=WivktIwNAFGVIITYRJ6Wm_vuU5zso8QHMrq1IWj3ItY,13477 +transformers/models/seamless_m4t/modeling_seamless_m4t.py,sha256=cE9d72QCI4m5Ri6yadC0FpsGZKM3PtrJkvSVpso41Xw,185858 +transformers/models/seamless_m4t/processing_seamless_m4t.py,sha256=S7sWW_Ce-nzRLlkziyqfZ3G8E6iw3yjSVfmsEOV9-NY,3119 +transformers/models/seamless_m4t/tokenization_seamless_m4t.py,sha256=abW0ypMlSxwi08aygOfipsvezAWAI0JSpzZriwGGusk,18201 +transformers/models/seamless_m4t_v2/__init__.py,sha256=mMY04PBMrOwTIQLq01RHqZjssvrSYl3UDhP5Y5vFifs,1011 +transformers/models/seamless_m4t_v2/__pycache__/__init__.cpython-310.pyc,, +transformers/models/seamless_m4t_v2/__pycache__/configuration_seamless_m4t_v2.cpython-310.pyc,, +transformers/models/seamless_m4t_v2/__pycache__/modeling_seamless_m4t_v2.cpython-310.pyc,, +transformers/models/seamless_m4t_v2/configuration_seamless_m4t_v2.py,sha256=APw6nlgt9bbFoZmib1qhAAl2emvGMlVIJG3J2EPpOHE,24437 +transformers/models/seamless_m4t_v2/modeling_seamless_m4t_v2.py,sha256=CWcVKf_jMcWIM9XVCTmGMuXSMz1k4bbw1WkQjDTTeHk,203615 +transformers/models/seed_oss/__init__.py,sha256=ukqpfG-W3jFJvA9UiL5bI_2jl_CTZFynUL0Tq9WD63M,1025 +transformers/models/seed_oss/__pycache__/__init__.cpython-310.pyc,, +transformers/models/seed_oss/__pycache__/configuration_seed_oss.cpython-310.pyc,, +transformers/models/seed_oss/__pycache__/modeling_seed_oss.cpython-310.pyc,, +transformers/models/seed_oss/__pycache__/modular_seed_oss.cpython-310.pyc,, +transformers/models/seed_oss/configuration_seed_oss.py,sha256=lD6CXsMZcLufiIZliAsYO-EkuKCVmYzQbOFOWp_LfWo,9288 +transformers/models/seed_oss/modeling_seed_oss.py,sha256=ocGsDdC3CQ9gakGyToK0zVzL_LMDdLFC4VhVoX69J6M,23064 +transformers/models/seed_oss/modular_seed_oss.py,sha256=acPdowxks5362oPsZe2Qp_K4SWAzjaarUGKbxyvMx98,7493 +transformers/models/segformer/__init__.py,sha256=eE8wZP6VldFpYlnLQ_cNptaXwdK5-bDtlVlmSDL8_lA,1144 +transformers/models/segformer/__pycache__/__init__.cpython-310.pyc,, +transformers/models/segformer/__pycache__/configuration_segformer.cpython-310.pyc,, +transformers/models/segformer/__pycache__/image_processing_segformer.cpython-310.pyc,, +transformers/models/segformer/__pycache__/image_processing_segformer_fast.cpython-310.pyc,, +transformers/models/segformer/__pycache__/modeling_segformer.cpython-310.pyc,, +transformers/models/segformer/__pycache__/modular_segformer.cpython-310.pyc,, +transformers/models/segformer/configuration_segformer.py,sha256=Lapbj-S02yQRDsSuAIJWfsWXUcmp_7Dx0QvFZWxyaYM,6392 +transformers/models/segformer/image_processing_segformer.py,sha256=juerbcOkQrS2sJvi-EBO1QL07O754OAuQ9h71ahS9mw,22215 +transformers/models/segformer/image_processing_segformer_fast.py,sha256=YCoA1J9dlDrPEvVW9gffgbzoobwoVWOVamEKASaFQJg,9363 +transformers/models/segformer/modeling_segformer.py,sha256=IzIL49_DnPgMh2vaII1nXM7NC6RXEBRF6YnycyN66n0,28991 +transformers/models/segformer/modular_segformer.py,sha256=yzCXC7Dlmyrc3Zp_JmPRPtiusnXuQY-ePkwnLnQo0Xo,5636 +transformers/models/seggpt/__init__.py,sha256=RzV8DKCX1lOWGqXv2BlE1R7T4QuEcdYAVy_csccLvEw,1036 +transformers/models/seggpt/__pycache__/__init__.cpython-310.pyc,, +transformers/models/seggpt/__pycache__/configuration_seggpt.cpython-310.pyc,, +transformers/models/seggpt/__pycache__/image_processing_seggpt.cpython-310.pyc,, +transformers/models/seggpt/__pycache__/modeling_seggpt.cpython-310.pyc,, +transformers/models/seggpt/configuration_seggpt.py,sha256=2YaJ3zkHkbISR7sdH5jML4yYNY4Ml8a-pDNoV9m6WKU,6477 +transformers/models/seggpt/image_processing_seggpt.py,sha256=4KQEdDiiNTGiaEeYyQ94DMYGbnKTWK5KPnsEi2BjvRo,30820 +transformers/models/seggpt/modeling_seggpt.py,sha256=0xPSDp_aQq2fl90dHFxMRjWYfd8vZD6U2PpjDOfWhh0,43402 +transformers/models/sew/__init__.py,sha256=POCF36ZRa_dr7oQhkDU2X17bsZuLoWI5V8DSihqr_vU,987 +transformers/models/sew/__pycache__/__init__.cpython-310.pyc,, +transformers/models/sew/__pycache__/configuration_sew.cpython-310.pyc,, +transformers/models/sew/__pycache__/modeling_sew.cpython-310.pyc,, +transformers/models/sew/__pycache__/modular_sew.cpython-310.pyc,, +transformers/models/sew/configuration_sew.py,sha256=cQWYOkXSHJn16vbN1if1tYc06dFX74DRcNbwlr-rEfc,14258 +transformers/models/sew/modeling_sew.py,sha256=uQmbKMMM5WPlk-QkMWFe-jB23Ynnb32lfd5EHoWDQyM,46258 +transformers/models/sew/modular_sew.py,sha256=jvJtKB3hWWUVXthqVyN6T3EayNL58eMAt7uFwVnWhjI,18366 +transformers/models/sew_d/__init__.py,sha256=zE9sw10e_a1d-8-Jsb75z5frCjkFGD0dZMHAXiNgGwk,991 +transformers/models/sew_d/__pycache__/__init__.cpython-310.pyc,, +transformers/models/sew_d/__pycache__/configuration_sew_d.cpython-310.pyc,, +transformers/models/sew_d/__pycache__/modeling_sew_d.cpython-310.pyc,, +transformers/models/sew_d/configuration_sew_d.py,sha256=37FIejX37vzb-ue4jTBBThMJscKBwzN9skAnkMk5pVs,16218 +transformers/models/sew_d/modeling_sew_d.py,sha256=YNVMZIOzRMm-j2GuwqPTPSLIzS9jb7yPnjYppehQXfY,67814 +transformers/models/shieldgemma2/__init__.py,sha256=B7eqFJSWi0p49QNvKqUGR8NPyFjQuMdBANevIjTsSxw,1048 +transformers/models/shieldgemma2/__pycache__/__init__.cpython-310.pyc,, +transformers/models/shieldgemma2/__pycache__/configuration_shieldgemma2.cpython-310.pyc,, +transformers/models/shieldgemma2/__pycache__/modeling_shieldgemma2.cpython-310.pyc,, +transformers/models/shieldgemma2/__pycache__/processing_shieldgemma2.cpython-310.pyc,, +transformers/models/shieldgemma2/configuration_shieldgemma2.py,sha256=nQMUdufngEg6ggjk1EiFmdMSswo_bl79ubYIOiZSYiM,4790 +transformers/models/shieldgemma2/modeling_shieldgemma2.py,sha256=T--g5k0drCkyx7t8fOvNIZUaCbgsKFg5jYYfX3TPgaQ,5745 +transformers/models/shieldgemma2/processing_shieldgemma2.py,sha256=CIomoND_vEP_UIHYq8qiXVlftrDj6W8NEYql4S3554E,8432 +transformers/models/siglip/__init__.py,sha256=CnNqbSQ25tKLz0MGJVmhSXjVyASRDu7v5yjTHWYZ6M4,1160 +transformers/models/siglip/__pycache__/__init__.cpython-310.pyc,, +transformers/models/siglip/__pycache__/configuration_siglip.cpython-310.pyc,, +transformers/models/siglip/__pycache__/image_processing_siglip.cpython-310.pyc,, +transformers/models/siglip/__pycache__/image_processing_siglip_fast.cpython-310.pyc,, +transformers/models/siglip/__pycache__/modeling_siglip.cpython-310.pyc,, +transformers/models/siglip/__pycache__/processing_siglip.cpython-310.pyc,, +transformers/models/siglip/__pycache__/tokenization_siglip.cpython-310.pyc,, +transformers/models/siglip/configuration_siglip.py,sha256=rJUIBo2XZ_7Mi9MTN9lD16Uik3qfhoTWJ6HeIdDpZqI,11928 +transformers/models/siglip/image_processing_siglip.py,sha256=ET692vmQ5--PBUKciSU_A7mzY1WMPBL2YgFgL7mPHgo,11690 +transformers/models/siglip/image_processing_siglip_fast.py,sha256=TcuuuktjwSBXhPnjRkEhFydFlfB-5VhXB3Cgk07kjFk,1242 +transformers/models/siglip/modeling_siglip.py,sha256=foyedsMvEB7hJWJ87MnPGOOD7aRDV2u1o1nnme8Jf1o,38783 +transformers/models/siglip/processing_siglip.py,sha256=aOQ5MSoMpf_MFh1vt2truSm1Y0oFpHCSZX77G1oRUIc,915 +transformers/models/siglip/tokenization_siglip.py,sha256=CmnaWyjLTBJ5p5DnFcfNAGz9yQ119FPZ0jUc-4RE9Ho,14286 +transformers/models/siglip2/__init__.py,sha256=amD21WA9L0J-5pYBJuPdbekOq5RaFpKX5mq3IkKN7nE,1166 +transformers/models/siglip2/__pycache__/__init__.cpython-310.pyc,, +transformers/models/siglip2/__pycache__/configuration_siglip2.cpython-310.pyc,, +transformers/models/siglip2/__pycache__/image_processing_siglip2.cpython-310.pyc,, +transformers/models/siglip2/__pycache__/image_processing_siglip2_fast.cpython-310.pyc,, +transformers/models/siglip2/__pycache__/modeling_siglip2.cpython-310.pyc,, +transformers/models/siglip2/__pycache__/modular_siglip2.cpython-310.pyc,, +transformers/models/siglip2/__pycache__/processing_siglip2.cpython-310.pyc,, +transformers/models/siglip2/__pycache__/tokenization_siglip2.cpython-310.pyc,, +transformers/models/siglip2/configuration_siglip2.py,sha256=NV0c1LVwB1fgM38_HpYYCbZfH_WaZWovhQlN6m95ltU,13052 +transformers/models/siglip2/image_processing_siglip2.py,sha256=nKfoXCYCjubtazBD4XsRWdaxSCd0W7fOY_Ki9yCZLls,16314 +transformers/models/siglip2/image_processing_siglip2_fast.py,sha256=83S8V9HcaL5k6cx2lPFXm__-L00YLP6JDhH_QSIwTVM,5590 +transformers/models/siglip2/modeling_siglip2.py,sha256=Cr3CCUs7oeSvJX0__SapaEl0lpAkNkJ_CuxOlpSdCxA,45949 +transformers/models/siglip2/modular_siglip2.py,sha256=VeqVdyc3zi9w-JPJ9PO9z70eZVpza5kkiDdsKtFE6eo,27461 +transformers/models/siglip2/processing_siglip2.py,sha256=JIEHRW0qhiZyc7jxo52jeIVyNhuCegfXPYN-aN-gxBk,1315 +transformers/models/siglip2/tokenization_siglip2.py,sha256=LyGmG3uuOaIF4ccbJ8sgdOYYlbOX-6ujOFIReAqz02I,3909 +transformers/models/smollm3/__init__.py,sha256=BZA2MiDpGmv2swg1yO14tkgi_SZ0yVg8ndr-PJwY-fI,1000 +transformers/models/smollm3/__pycache__/__init__.cpython-310.pyc,, +transformers/models/smollm3/__pycache__/configuration_smollm3.cpython-310.pyc,, +transformers/models/smollm3/__pycache__/modeling_smollm3.cpython-310.pyc,, +transformers/models/smollm3/__pycache__/modular_smollm3.cpython-310.pyc,, +transformers/models/smollm3/configuration_smollm3.py,sha256=kEq26TJk8occ-prslZWkzQLXPmDtysBMEbXFsvwTD5s,10686 +transformers/models/smollm3/modeling_smollm3.py,sha256=t0IcBDfgmfLT09PzT0HaA2ytbcP1QHRbsn69Etr7JMM,23481 +transformers/models/smollm3/modular_smollm3.py,sha256=wiI53MmZXi4jKPqru7vYLrs1tTh0unj2ajTgl5tKtDQ,13617 +transformers/models/smolvlm/__init__.py,sha256=fE-znTLrbxNe5qkHVgI4xmwFz-paFymZuxTAd2GKkOo,1126 +transformers/models/smolvlm/__pycache__/__init__.cpython-310.pyc,, +transformers/models/smolvlm/__pycache__/configuration_smolvlm.cpython-310.pyc,, +transformers/models/smolvlm/__pycache__/image_processing_smolvlm.cpython-310.pyc,, +transformers/models/smolvlm/__pycache__/image_processing_smolvlm_fast.cpython-310.pyc,, +transformers/models/smolvlm/__pycache__/modeling_smolvlm.cpython-310.pyc,, +transformers/models/smolvlm/__pycache__/modular_smolvlm.cpython-310.pyc,, +transformers/models/smolvlm/__pycache__/processing_smolvlm.cpython-310.pyc,, +transformers/models/smolvlm/__pycache__/video_processing_smolvlm.cpython-310.pyc,, +transformers/models/smolvlm/configuration_smolvlm.py,sha256=nFF2ntArNkX8aNtpH_zo-89_tG8E-N1rsuZkibV1S60,9233 +transformers/models/smolvlm/image_processing_smolvlm.py,sha256=0MoOYenoWEsoO_HAVBtp9BhTQ3WK31kN0NOdnmKwiK4,44693 +transformers/models/smolvlm/image_processing_smolvlm_fast.py,sha256=PLlFsjY1r_vR4u-ECWlgM0_O_GFeqawdIf1YljRjSjQ,23757 +transformers/models/smolvlm/modeling_smolvlm.py,sha256=Yd4JYkBZ4idmSH5KyMLrAy7u_c9LGf5JYrzC3lqpnd8,39761 +transformers/models/smolvlm/modular_smolvlm.py,sha256=zWv7SX5J3OAAEqcR7uMFNj3bqaDiMuXX9AAii5RRr1s,19479 +transformers/models/smolvlm/processing_smolvlm.py,sha256=rXRZZlbeM5NfRnJ-woJ9S_EWV1weSiMbDBFaL0SwOec,15692 +transformers/models/smolvlm/video_processing_smolvlm.py,sha256=pcG0gLb8PqlKhsOxkocVr3--szcgq46_M0bcWaQM7Tk,14695 +transformers/models/solar_open/__init__.py,sha256=_IuMoJHTvrxSNxcHGJe1QpLINdHuEUV7BeCLSQkzPgs,1001 +transformers/models/solar_open/__pycache__/__init__.cpython-310.pyc,, +transformers/models/solar_open/__pycache__/configuration_solar_open.cpython-310.pyc,, +transformers/models/solar_open/__pycache__/modeling_solar_open.cpython-310.pyc,, +transformers/models/solar_open/__pycache__/modular_solar_open.cpython-310.pyc,, +transformers/models/solar_open/configuration_solar_open.py,sha256=dKi-RP9xdkNW53a8zEzRxvM_I3YK-Ed6Kbu2eu3bhz0,9009 +transformers/models/solar_open/modeling_solar_open.py,sha256=tmZlhJ97PaG_FLYPoCDyqn812R0fsoGfOioxUy2_UBE,28056 +transformers/models/solar_open/modular_solar_open.py,sha256=8RBDInB7N2D8CZZ-TC9FDd0kiabkagyK5MzhpHrFg1w,9019 +transformers/models/speech_encoder_decoder/__init__.py,sha256=YJ8Vz0n_ZDxYjI_2r-G3iRCoKQy58r8C1n4t2s42BSw,1025 +transformers/models/speech_encoder_decoder/__pycache__/__init__.cpython-310.pyc,, +transformers/models/speech_encoder_decoder/__pycache__/configuration_speech_encoder_decoder.cpython-310.pyc,, +transformers/models/speech_encoder_decoder/__pycache__/modeling_speech_encoder_decoder.cpython-310.pyc,, +transformers/models/speech_encoder_decoder/configuration_speech_encoder_decoder.py,sha256=SbTPozwtY1VUN2HqM69NpHUrvDHor7uF4UnB7xWSwlg,4678 +transformers/models/speech_encoder_decoder/modeling_speech_encoder_decoder.py,sha256=Ho1rUWNaNvc9N3wsbfHXOG9D1QXdyO93iyzr7IJn9kg,24600 +transformers/models/speech_to_text/__init__.py,sha256=HmMO19XDk0Inzvsd1Kgxdr7JYZMA1UrjEEqPT1f9ksI,1154 +transformers/models/speech_to_text/__pycache__/__init__.cpython-310.pyc,, +transformers/models/speech_to_text/__pycache__/configuration_speech_to_text.cpython-310.pyc,, +transformers/models/speech_to_text/__pycache__/feature_extraction_speech_to_text.cpython-310.pyc,, +transformers/models/speech_to_text/__pycache__/modeling_speech_to_text.cpython-310.pyc,, +transformers/models/speech_to_text/__pycache__/processing_speech_to_text.cpython-310.pyc,, +transformers/models/speech_to_text/__pycache__/tokenization_speech_to_text.cpython-310.pyc,, +transformers/models/speech_to_text/configuration_speech_to_text.py,sha256=a90toFpnPdWA6L7WDjj5dfdIf5rkcVRC0hnCyGwL5Jg,9987 +transformers/models/speech_to_text/feature_extraction_speech_to_text.py,sha256=-e_x4Qob2NkK8Uuy0H7szz9CxlwcZmCJLN7d_vemOXc,13798 +transformers/models/speech_to_text/modeling_speech_to_text.py,sha256=_EVIwqCbbeoe4fHlCfcGMciqvGmkyocqqLckyeBfE7g,51433 +transformers/models/speech_to_text/processing_speech_to_text.py,sha256=EMa7GGoDf3TA-2Xec8TRiate7Lj22VIjmijDtmae-I0,1770 +transformers/models/speech_to_text/tokenization_speech_to_text.py,sha256=JZrzUriA7dZnQoHtJ81lODxqxbZprXT3qWht7mpqf5A,11455 +transformers/models/speecht5/__init__.py,sha256=DploRLnZX4ZO40Z7BstCZ7aNWGuZE06tIeMo0GTyR60,1124 +transformers/models/speecht5/__pycache__/__init__.cpython-310.pyc,, +transformers/models/speecht5/__pycache__/configuration_speecht5.cpython-310.pyc,, +transformers/models/speecht5/__pycache__/feature_extraction_speecht5.cpython-310.pyc,, +transformers/models/speecht5/__pycache__/modeling_speecht5.cpython-310.pyc,, +transformers/models/speecht5/__pycache__/number_normalizer.cpython-310.pyc,, +transformers/models/speecht5/__pycache__/processing_speecht5.cpython-310.pyc,, +transformers/models/speecht5/__pycache__/tokenization_speecht5.cpython-310.pyc,, +transformers/models/speecht5/configuration_speecht5.py,sha256=Yi-v_PX_QmYOjlqxHH1vNNzWYa3lesHQZ-pdGoOOunM,23513 +transformers/models/speecht5/feature_extraction_speecht5.py,sha256=xMEQ55FOnnFirIQCFrFYWuhjHDiTI-MAWJtOMFRT7jM,16724 +transformers/models/speecht5/modeling_speecht5.py,sha256=bRCwJjAXSLECPg6mX6Yd2AHUXquGMNkkalQELyEYizk,140410 +transformers/models/speecht5/number_normalizer.py,sha256=L9vC3QKmC_27nv978ifR-f4gkCCgw2aMjpqqFrpDJEA,7004 +transformers/models/speecht5/processing_speecht5.py,sha256=rUA2C5j1-VxIbKBaGeFgYChGTVjPPtuEskeYCC8fglY,5373 +transformers/models/speecht5/tokenization_speecht5.py,sha256=39_jjTEYCN-CEqALP6R53KA0ZnaI220gUGf8jNS1T6U,6688 +transformers/models/splinter/__init__.py,sha256=N3tdgJIqZRPK0g3pfLE3p3-HkGJMRf-GQ189anQ51to,1084 +transformers/models/splinter/__pycache__/__init__.cpython-310.pyc,, +transformers/models/splinter/__pycache__/configuration_splinter.cpython-310.pyc,, +transformers/models/splinter/__pycache__/modeling_splinter.cpython-310.pyc,, +transformers/models/splinter/__pycache__/tokenization_splinter.cpython-310.pyc,, +transformers/models/splinter/configuration_splinter.py,sha256=ZXuO3ly1JWDPbyooq2A5IHlgDx-tW3iMrg5VlnU2M1k,5478 +transformers/models/splinter/modeling_splinter.py,sha256=CXG3euyfY8RmRMv0MXcQmBSVk0Cpo0_2Y9fm4fiJ_cg,34676 +transformers/models/splinter/tokenization_splinter.py,sha256=hm-SaCCy7IhVgH5ZztphxXctnoOZ8iK7Mqad-P0o44s,6692 +transformers/models/squeezebert/__init__.py,sha256=N2L22551dhssCbWpQgWZJ172TnRjxUdnRlSKr8xW48w,1092 +transformers/models/squeezebert/__pycache__/__init__.cpython-310.pyc,, +transformers/models/squeezebert/__pycache__/configuration_squeezebert.cpython-310.pyc,, +transformers/models/squeezebert/__pycache__/modeling_squeezebert.cpython-310.pyc,, +transformers/models/squeezebert/__pycache__/tokenization_squeezebert.cpython-310.pyc,, +transformers/models/squeezebert/configuration_squeezebert.py,sha256=yGlfsxFyzQXIJ4BtZnsWRolyWQ8knXPgLIvaW4MTBkE,7062 +transformers/models/squeezebert/modeling_squeezebert.py,sha256=8NZgDopn4y31WXVJM_Yu0ZkRUWbPYYQTJsT9aorPISQ,36318 +transformers/models/squeezebert/tokenization_squeezebert.py,sha256=U8LyiVJ_oBc5ejnes_tLUB2espGVrNiqDiVZtsrEOqI,1011 +transformers/models/stablelm/__init__.py,sha256=aVgWTcwBuuiGJDp8H_ZU6BvhYqjmNEqCukU7jEfwd_I,997 +transformers/models/stablelm/__pycache__/__init__.cpython-310.pyc,, +transformers/models/stablelm/__pycache__/configuration_stablelm.cpython-310.pyc,, +transformers/models/stablelm/__pycache__/modeling_stablelm.cpython-310.pyc,, +transformers/models/stablelm/configuration_stablelm.py,sha256=RsNj81u-0HFqcBcErO5NqHwCZLGK2dVEvEIgAZ2bGWY,8003 +transformers/models/stablelm/modeling_stablelm.py,sha256=RPUZEjBS3vV9uYAP4h_mHiYYSlt9TMdxPlO3jmRWWxM,29077 +transformers/models/starcoder2/__init__.py,sha256=fZ8HHZCGjxRfVgROe7zuoi9ADIAa4SeqxGHkvKUQiQM,1001 +transformers/models/starcoder2/__pycache__/__init__.cpython-310.pyc,, +transformers/models/starcoder2/__pycache__/configuration_starcoder2.cpython-310.pyc,, +transformers/models/starcoder2/__pycache__/modeling_starcoder2.cpython-310.pyc,, +transformers/models/starcoder2/__pycache__/modular_starcoder2.cpython-310.pyc,, +transformers/models/starcoder2/configuration_starcoder2.py,sha256=7Jf-ghDpzdedGYw-rDgdnAPgmQDfyEivykh7zLtU2RM,8397 +transformers/models/starcoder2/modeling_starcoder2.py,sha256=tcVkxqR-KRZTm4gl__HsVvYYDdUMcuBBpOQoJJkXwsE,22480 +transformers/models/starcoder2/modular_starcoder2.py,sha256=egeMseHaVO_t4ZD4pxOCn58VqWAKmrre_AOgYP8r3So,9523 +transformers/models/superglue/__init__.py,sha256=MIQs2BH0RmiKt3rZwwW28v4HKdE-nOX3uU2O0dUwYQA,1096 +transformers/models/superglue/__pycache__/__init__.cpython-310.pyc,, +transformers/models/superglue/__pycache__/configuration_superglue.cpython-310.pyc,, +transformers/models/superglue/__pycache__/image_processing_superglue.cpython-310.pyc,, +transformers/models/superglue/__pycache__/image_processing_superglue_fast.cpython-310.pyc,, +transformers/models/superglue/__pycache__/modeling_superglue.cpython-310.pyc,, +transformers/models/superglue/configuration_superglue.py,sha256=3QyEeKVWxJCZ4AlVLiNfw4UQaFK4Ke8qKbxgzd7M38c,5659 +transformers/models/superglue/image_processing_superglue.py,sha256=dlYdXa8IIMvXZXEshy3VyXaQsDKlwEwFRzZQujiYOKY,21963 +transformers/models/superglue/image_processing_superglue_fast.py,sha256=ALeMIam25GAPCtLW_pwLrPU4TWSI7lfqQsOHK1puNZI,12487 +transformers/models/superglue/modeling_superglue.py,sha256=bX7uwwrSgXDiMp-EX8rc13WpHf407d0SecRzIfg0VTQ,32597 +transformers/models/superpoint/__init__.py,sha256=6fQQ-p4220IUaIQCZseKItiHWVV7KOiA5mXoTdJSJmI,1100 +transformers/models/superpoint/__pycache__/__init__.cpython-310.pyc,, +transformers/models/superpoint/__pycache__/configuration_superpoint.cpython-310.pyc,, +transformers/models/superpoint/__pycache__/image_processing_superpoint.cpython-310.pyc,, +transformers/models/superpoint/__pycache__/image_processing_superpoint_fast.cpython-310.pyc,, +transformers/models/superpoint/__pycache__/modeling_superpoint.cpython-310.pyc,, +transformers/models/superpoint/configuration_superpoint.py,sha256=ukYp0RbUXxjIOBsTjyHEWToI_ATxWkaEYxKCiK8tRM8,4048 +transformers/models/superpoint/image_processing_superpoint.py,sha256=2Dzp4DObwxyQy8z3HPb02ZvHqqPeJNCzLF1Ifr07UWM,16373 +transformers/models/superpoint/image_processing_superpoint_fast.py,sha256=jpnXXEn9LpabylUAqDBmg6Cl2jzUfTiPVma3CRNb6eA,6444 +transformers/models/superpoint/modeling_superpoint.py,sha256=B3pg1NRWe5bZGyvsop-ygbST4B26uvuGPmNQx6AsrDc,19490 +transformers/models/swiftformer/__init__.py,sha256=PDcV6Hp4K5CT7w3dsfXb3c9Rd2fgIw7_WLTOH4JQgJU,1003 +transformers/models/swiftformer/__pycache__/__init__.cpython-310.pyc,, +transformers/models/swiftformer/__pycache__/configuration_swiftformer.cpython-310.pyc,, +transformers/models/swiftformer/__pycache__/modeling_swiftformer.cpython-310.pyc,, +transformers/models/swiftformer/configuration_swiftformer.py,sha256=j3WQK5w4uGcTu7divgCdKcYilJ96ubrvj8-jbAzGF7Q,5285 +transformers/models/swiftformer/modeling_swiftformer.py,sha256=Frj9a3bHP_WcV7T3hYxKqn2-ZY6W6XbGwutfC1dK6IM,19362 +transformers/models/swin/__init__.py,sha256=upidQvan2_lviVSI8s92-qKh7-Z28XC9Ug9aMV1wnjc,989 +transformers/models/swin/__pycache__/__init__.cpython-310.pyc,, +transformers/models/swin/__pycache__/configuration_swin.cpython-310.pyc,, +transformers/models/swin/__pycache__/modeling_swin.cpython-310.pyc,, +transformers/models/swin/configuration_swin.py,sha256=N9hPwOaVcuBou_Uu9sHJR2Ij8VAZ1-FcOgb57B_bRXs,7245 +transformers/models/swin/modeling_swin.py,sha256=OrCE0dtp8vkLXMx56_FNGcfZWxzUD0xuANzDSzk-0Vc,50971 +transformers/models/swin2sr/__init__.py,sha256=PLCBXwTQF37hLur2ROcYXUiNropQ6u5Ig_HgK29MOu8,1088 +transformers/models/swin2sr/__pycache__/__init__.cpython-310.pyc,, +transformers/models/swin2sr/__pycache__/configuration_swin2sr.cpython-310.pyc,, +transformers/models/swin2sr/__pycache__/image_processing_swin2sr.cpython-310.pyc,, +transformers/models/swin2sr/__pycache__/image_processing_swin2sr_fast.cpython-310.pyc,, +transformers/models/swin2sr/__pycache__/modeling_swin2sr.cpython-310.pyc,, +transformers/models/swin2sr/configuration_swin2sr.py,sha256=H7d6JCeERB-MABZd32v4phemlfgpZ9HHLqYu7h4ROEs,6826 +transformers/models/swin2sr/image_processing_swin2sr.py,sha256=noC9l79H7O4JI3jBzrQvbtjB8eTTLUVnXqZYbni4Cok,9022 +transformers/models/swin2sr/image_processing_swin2sr_fast.py,sha256=RtgcJHyjgUReOTVdOJcliBv5rCFxmwCdblS_EqZNrns,3581 +transformers/models/swin2sr/modeling_swin2sr.py,sha256=WP7fJapYr8TcrVmKwXgSNhe7U9h8LGJ10ivwOJ9Dq_Q,44865 +transformers/models/swinv2/__init__.py,sha256=njM902tlEQ82mYRN9ZTMOiXpJn1NHnxKbm_LCvn2I-M,993 +transformers/models/swinv2/__pycache__/__init__.cpython-310.pyc,, +transformers/models/swinv2/__pycache__/configuration_swinv2.cpython-310.pyc,, +transformers/models/swinv2/__pycache__/modeling_swinv2.cpython-310.pyc,, +transformers/models/swinv2/configuration_swinv2.py,sha256=ESpjaqr-z2lYBYap7n_p_KT5YSuna5-UzxhtUAZBQpI,7387 +transformers/models/swinv2/modeling_swinv2.py,sha256=-mLDTHu0PRkit2bIINWNxGzM9cG3bi8vs3mkTIfte5I,55854 +transformers/models/switch_transformers/__init__.py,sha256=Iw38A9kfIT5mJ0G00YE-TVN-M_b1DBHYQqb0pEyTZMY,1019 +transformers/models/switch_transformers/__pycache__/__init__.cpython-310.pyc,, +transformers/models/switch_transformers/__pycache__/configuration_switch_transformers.cpython-310.pyc,, +transformers/models/switch_transformers/__pycache__/modeling_switch_transformers.cpython-310.pyc,, +transformers/models/switch_transformers/__pycache__/modular_switch_transformers.cpython-310.pyc,, +transformers/models/switch_transformers/configuration_switch_transformers.py,sha256=l_-9fdSLwhK5beVtT92WQLfwcA7aztFZ3YsHz4yNOZU,9764 +transformers/models/switch_transformers/modeling_switch_transformers.py,sha256=Wro7-wQWozg8ocdvJ1yRZQ8h_MXCu2eNRLW5iF6D1B4,51175 +transformers/models/switch_transformers/modular_switch_transformers.py,sha256=WaWgapx1FYQxHShIUlSTqoQt4DUWQCxZisRUOpY9qMI,35649 +transformers/models/t5/__init__.py,sha256=ieynYXP35xsyLPJPIK2Xjq4FtzCq_5aI5Kg7i3kHF44,1020 +transformers/models/t5/__pycache__/__init__.cpython-310.pyc,, +transformers/models/t5/__pycache__/configuration_t5.cpython-310.pyc,, +transformers/models/t5/__pycache__/modeling_t5.cpython-310.pyc,, +transformers/models/t5/__pycache__/tokenization_t5.cpython-310.pyc,, +transformers/models/t5/configuration_t5.py,sha256=oW1L-AiyeNJ5RV-ADiBgbRmnsdHVE7gGH-K0wkxUhi0,6843 +transformers/models/t5/modeling_t5.py,sha256=iz7prwIyktEMpjBxeZvVF0phOi66ExNcP4DvvZuYPlQ,73290 +transformers/models/t5/tokenization_t5.py,sha256=b6ZpaqK_a_QLzXx66oG1tYHjZa2kXG13aNU2CRdEltU,6540 +transformers/models/t5gemma/__init__.py,sha256=S7m_HiGfMyAtU_CSHx9VTNPtSxcnLp8V67FCSGHpLCs,995 +transformers/models/t5gemma/__pycache__/__init__.cpython-310.pyc,, +transformers/models/t5gemma/__pycache__/configuration_t5gemma.cpython-310.pyc,, +transformers/models/t5gemma/__pycache__/modeling_t5gemma.cpython-310.pyc,, +transformers/models/t5gemma/__pycache__/modular_t5gemma.cpython-310.pyc,, +transformers/models/t5gemma/configuration_t5gemma.py,sha256=R-0SAm_jGrppoDHOtJrzQieBmcwVkLE-Wntt8kkDdIc,15101 +transformers/models/t5gemma/modeling_t5gemma.py,sha256=GbqboVUVHqW9t8i_T2DCZRG3pamFvf7DEalbBK4QGiM,59441 +transformers/models/t5gemma/modular_t5gemma.py,sha256=L5CQ-3GMlifmxDTvi2Cn8drS7m_xVccEVt5ufKgDOTk,59460 +transformers/models/t5gemma2/__init__.py,sha256=AF59388HsGjMPsRnN8iRdDNwYBE-uyTZ-U8zEKnYRyI,997 +transformers/models/t5gemma2/__pycache__/__init__.cpython-310.pyc,, +transformers/models/t5gemma2/__pycache__/configuration_t5gemma2.cpython-310.pyc,, +transformers/models/t5gemma2/__pycache__/modeling_t5gemma2.cpython-310.pyc,, +transformers/models/t5gemma2/__pycache__/modular_t5gemma2.cpython-310.pyc,, +transformers/models/t5gemma2/configuration_t5gemma2.py,sha256=JtTLSiiBpn457Khol0yb7pgnDzQxjpU_PaiUCfYLchU,32013 +transformers/models/t5gemma2/modeling_t5gemma2.py,sha256=4C5v7Hc72XbtlcxXkvbkQSJFjeJBp4GKv9QFOt2Ewio,69830 +transformers/models/t5gemma2/modular_t5gemma2.py,sha256=GkkhdpRY58Dh81W-jI2r4Z_xqmynjN1pYtYYhlrav5g,71892 +transformers/models/table_transformer/__init__.py,sha256=VT-KM0_6LZ6fdOAglbfA8zEhCQuYa6He10Div7WEcD8,1015 +transformers/models/table_transformer/__pycache__/__init__.cpython-310.pyc,, +transformers/models/table_transformer/__pycache__/configuration_table_transformer.cpython-310.pyc,, +transformers/models/table_transformer/__pycache__/modeling_table_transformer.cpython-310.pyc,, +transformers/models/table_transformer/configuration_table_transformer.py,sha256=49Zsj_wrs68-zpbLVhmvporuW1QZuMJmdDGcY6o7SSg,10542 +transformers/models/table_transformer/modeling_table_transformer.py,sha256=iRtCCXNcrXo-UvCT2zNrlvQNK4rTgDLxq8f1hAEHJQw,60017 +transformers/models/tapas/__init__.py,sha256=Q4UNvDF5OHuAeLJFMEeBOGKzgO-ytt4t8x9shTlIb2o,1029 +transformers/models/tapas/__pycache__/__init__.cpython-310.pyc,, +transformers/models/tapas/__pycache__/configuration_tapas.cpython-310.pyc,, +transformers/models/tapas/__pycache__/modeling_tapas.cpython-310.pyc,, +transformers/models/tapas/__pycache__/tokenization_tapas.cpython-310.pyc,, +transformers/models/tapas/configuration_tapas.py,sha256=HEuGt4xfYL76dKmRJke5rf5Njp_cyNSfjFyAngCBdFA,12670 +transformers/models/tapas/modeling_tapas.py,sha256=OzFA3xXoPbftwqX2quM7t4EmC2QEcqvey6AmaxjHfhU,98183 +transformers/models/tapas/tokenization_tapas.py,sha256=ZE9MRtaO7G4rOuyJvBrYUtkmNyfLDbl806ooj99y350,119179 +transformers/models/textnet/__init__.py,sha256=nqXafUk5z5F_61jrGF9gK_sI66uj7kq5sUYrit9bsno,1088 +transformers/models/textnet/__pycache__/__init__.cpython-310.pyc,, +transformers/models/textnet/__pycache__/configuration_textnet.cpython-310.pyc,, +transformers/models/textnet/__pycache__/image_processing_textnet.cpython-310.pyc,, +transformers/models/textnet/__pycache__/image_processing_textnet_fast.cpython-310.pyc,, +transformers/models/textnet/__pycache__/modeling_textnet.cpython-310.pyc,, +transformers/models/textnet/configuration_textnet.py,sha256=KS3u663CIUCLwZJAoAX3rj07wnKzycYR1phc3-L6fSE,6042 +transformers/models/textnet/image_processing_textnet.py,sha256=2QKffUUBxTaIQjM22LGyImy6kfNIYVOOiQDBeHwzi-o,17488 +transformers/models/textnet/image_processing_textnet_fast.py,sha256=T0XfPLeYHWHuY7xVqmId4_33W7utVwWhNT6tWf2su4I,5336 +transformers/models/textnet/modeling_textnet.py,sha256=tLOvHkgvXC6ABzXFl-tlQjasp5lgTjVIPCjJz3gw1VY,15152 +transformers/models/time_series_transformer/__init__.py,sha256=3A_3Wog-6NDwCoBIMtkzJv9slc_wXpzDzsOo-xBQ8hE,1027 +transformers/models/time_series_transformer/__pycache__/__init__.cpython-310.pyc,, +transformers/models/time_series_transformer/__pycache__/configuration_time_series_transformer.cpython-310.pyc,, +transformers/models/time_series_transformer/__pycache__/modeling_time_series_transformer.cpython-310.pyc,, +transformers/models/time_series_transformer/configuration_time_series_transformer.py,sha256=E8ZVYmOVp-xpGLcHBa9qRPtuJZNhzIEjbqM8kC8aRm0,11623 +transformers/models/time_series_transformer/modeling_time_series_transformer.py,sha256=uJzJmSJpeGKRIvAqRq7vd7zBWRlOg7XMoApTee4ueQc,84222 +transformers/models/timesfm/__init__.py,sha256=gcfLgRAbwZThFP98fst9wsoTMB0fkR28tzWYoQIs5qU,995 +transformers/models/timesfm/__pycache__/__init__.cpython-310.pyc,, +transformers/models/timesfm/__pycache__/configuration_timesfm.cpython-310.pyc,, +transformers/models/timesfm/__pycache__/modeling_timesfm.cpython-310.pyc,, +transformers/models/timesfm/__pycache__/modular_timesfm.cpython-310.pyc,, +transformers/models/timesfm/configuration_timesfm.py,sha256=cJB6lo5fzOTa9lCSlRxZKmETdkOWoLi6CMEG-UsRADk,5660 +transformers/models/timesfm/modeling_timesfm.py,sha256=yzGoNRUzLDP1YBN6MgJ5CFcY3O6jmFDmOWzLNnV5HSg,34600 +transformers/models/timesfm/modular_timesfm.py,sha256=mevT4diEVPt9qU9alD-hvmzeGUZGtizhh8QJTCOyfiE,32285 +transformers/models/timesfm2_5/__init__.py,sha256=QZR6P0hlbKuGdlvyWPJG8zbYV_5BC7-5ZEp6L3CdaNw,1002 +transformers/models/timesfm2_5/__pycache__/__init__.cpython-310.pyc,, +transformers/models/timesfm2_5/__pycache__/configuration_timesfm2_5.cpython-310.pyc,, +transformers/models/timesfm2_5/__pycache__/modeling_timesfm2_5.cpython-310.pyc,, +transformers/models/timesfm2_5/__pycache__/modular_timesfm2_5.cpython-310.pyc,, +transformers/models/timesfm2_5/configuration_timesfm2_5.py,sha256=ajekf8De28o-rif3TNMhHfeQLU_3bPkLFQQYpArfQ80,8043 +transformers/models/timesfm2_5/modeling_timesfm2_5.py,sha256=JQwbLxlV6glfzQBbB6j7CM8ac49A9sNnOrfOsr8rt3Q,40396 +transformers/models/timesfm2_5/modular_timesfm2_5.py,sha256=GzEMeHrC7Bv7-0qqw7Oe2-ryaxuUYB1Zzw-EfQahmRA,31179 +transformers/models/timesformer/__init__.py,sha256=4ODuyNRrYkbgpSbMHJX8XmpJdekHlu__zWey-plUSgI,1003 +transformers/models/timesformer/__pycache__/__init__.cpython-310.pyc,, +transformers/models/timesformer/__pycache__/configuration_timesformer.cpython-310.pyc,, +transformers/models/timesformer/__pycache__/modeling_timesformer.cpython-310.pyc,, +transformers/models/timesformer/configuration_timesformer.py,sha256=SNfbY5pVfjmLWMvTU7e_u3Xl7RORM6sYhMwZe4bs5J8,5553 +transformers/models/timesformer/modeling_timesformer.py,sha256=PmI4KdFLS9O8e84Qy-xygUq7X7RYcrEmCw56zYNiLGE,31911 +transformers/models/timm_backbone/__init__.py,sha256=s0GlTaJ43Yt9ZdzG9-qjJNlp0Ol4vjN-14S6N7gXLsA,1007 +transformers/models/timm_backbone/__pycache__/__init__.cpython-310.pyc,, +transformers/models/timm_backbone/__pycache__/configuration_timm_backbone.cpython-310.pyc,, +transformers/models/timm_backbone/__pycache__/modeling_timm_backbone.cpython-310.pyc,, +transformers/models/timm_backbone/configuration_timm_backbone.py,sha256=PISnTd3lvcAEHT_vwtR5l4v5xHpn2EXL5VXkhc-VU8g,4104 +transformers/models/timm_backbone/modeling_timm_backbone.py,sha256=36WvBIqZTx3KQ0UJzjI6izIKzFEZ28Xnr1xuIYZ37u8,6723 +transformers/models/timm_wrapper/__init__.py,sha256=U19BCtZcAQdmBto5bqG6u69W5rnUBtIyP11EcRh_0Tk,1054 +transformers/models/timm_wrapper/__pycache__/__init__.cpython-310.pyc,, +transformers/models/timm_wrapper/__pycache__/configuration_timm_wrapper.cpython-310.pyc,, +transformers/models/timm_wrapper/__pycache__/image_processing_timm_wrapper.cpython-310.pyc,, +transformers/models/timm_wrapper/__pycache__/modeling_timm_wrapper.cpython-310.pyc,, +transformers/models/timm_wrapper/configuration_timm_wrapper.py,sha256=N0WqUdR9u3l4ZqTmL2TumGGv3o8IQC1QxkE27YLpa-0,5583 +transformers/models/timm_wrapper/image_processing_timm_wrapper.py,sha256=ER8ITuGx1vIT2LWD4InZpkKZcC0i8RufGGDsGygexUA,5298 +transformers/models/timm_wrapper/modeling_timm_wrapper.py,sha256=D5uLjDglDhbbu2orrSJKYe5hxdZCekMmr4UmjGLnreo,16993 +transformers/models/trocr/__init__.py,sha256=Hllbq_42XbGRZyXsGOzYHcb33MOA5_yfijMRKEXJ4n4,1027 +transformers/models/trocr/__pycache__/__init__.cpython-310.pyc,, +transformers/models/trocr/__pycache__/configuration_trocr.cpython-310.pyc,, +transformers/models/trocr/__pycache__/modeling_trocr.cpython-310.pyc,, +transformers/models/trocr/__pycache__/processing_trocr.cpython-310.pyc,, +transformers/models/trocr/configuration_trocr.py,sha256=BPwCKrmq7wue_PIgm1z13g7O2qbnWjzMVVVsN6OQmkg,6793 +transformers/models/trocr/modeling_trocr.py,sha256=JPQIyx5aKtCho1UQetozzV470VpmEWH5Nol4wXVgxcU,35009 +transformers/models/trocr/processing_trocr.py,sha256=Ua_wrqvHlTgXiPiMSVgAe_axfYz8_IIknqCJaCDgFrc,2376 +transformers/models/tvp/__init__.py,sha256=zY4KwnUt4Q8f_afJGLIxUIfZf8RIyOOCbv9tnAJk1ic,1106 +transformers/models/tvp/__pycache__/__init__.cpython-310.pyc,, +transformers/models/tvp/__pycache__/configuration_tvp.cpython-310.pyc,, +transformers/models/tvp/__pycache__/image_processing_tvp.cpython-310.pyc,, +transformers/models/tvp/__pycache__/image_processing_tvp_fast.cpython-310.pyc,, +transformers/models/tvp/__pycache__/modeling_tvp.cpython-310.pyc,, +transformers/models/tvp/__pycache__/processing_tvp.cpython-310.pyc,, +transformers/models/tvp/configuration_tvp.py,sha256=WL2sz-5MRd1K_ccCScSixmJ8tAHuoD0dTG6q_o8hKpk,7541 +transformers/models/tvp/image_processing_tvp.py,sha256=vlfs7i3zGpbBjlECWnb3KyiGhaf7ySXtTWD6MNcAeTQ,22837 +transformers/models/tvp/image_processing_tvp_fast.py,sha256=O-U-aUWv-acg3ZjBjswQXA4_ukypOdlLRKbdN14VJsU,7866 +transformers/models/tvp/modeling_tvp.py,sha256=4tdxIK5ea8bnXTmXl4T2f1wIfhlqgUZcftPCoJGfwG0,37941 +transformers/models/tvp/processing_tvp.py,sha256=3pETNxZZvG6cD2JdlWcTU8qu62Pcz4joiPyCGu4J0xE,1973 +transformers/models/udop/__init__.py,sha256=GOiuT5Vm4kOkkZNVQ5AciUkw7BnJLB2quIn9jv9h5Nw,1061 +transformers/models/udop/__pycache__/__init__.cpython-310.pyc,, +transformers/models/udop/__pycache__/configuration_udop.cpython-310.pyc,, +transformers/models/udop/__pycache__/modeling_udop.cpython-310.pyc,, +transformers/models/udop/__pycache__/processing_udop.cpython-310.pyc,, +transformers/models/udop/__pycache__/tokenization_udop.cpython-310.pyc,, +transformers/models/udop/configuration_udop.py,sha256=9jlFhYuMYXt1ydwdUQyLPxn2I8NedxbybkiB6MMUHFI,8343 +transformers/models/udop/modeling_udop.py,sha256=HB7OmL6Q-sxcsLJe4Z8FIVfuQGZQNwDDqPArsUY7GaQ,79801 +transformers/models/udop/processing_udop.py,sha256=F78VvxPHlSEDUozH9cLrlSIFHCnPQn-QU-znDTKell4,7148 +transformers/models/udop/tokenization_udop.py,sha256=CblxD_A60VDOkDwNyt8Xthockkdi_wI_MyXyOZYFtt4,49668 +transformers/models/umt5/__init__.py,sha256=FKt6Ap3AvOCIKoeOM-5qY84lNEML9IujaDaYROINJMs,989 +transformers/models/umt5/__pycache__/__init__.cpython-310.pyc,, +transformers/models/umt5/__pycache__/configuration_umt5.cpython-310.pyc,, +transformers/models/umt5/__pycache__/modeling_umt5.cpython-310.pyc,, +transformers/models/umt5/configuration_umt5.py,sha256=pNMInuHXYS8UrXb8NGQu47DtswOSjAo7QZOSUsTjU80,6536 +transformers/models/umt5/modeling_umt5.py,sha256=dAaGlcUfkhqIiC-TCi5I8N2DRAYJ87vfZRyF3GhNvjI,75085 +transformers/models/unispeech/__init__.py,sha256=AXJMExDoYYI71OKNXhAt7lyqcFIvcLHEQ1Fsm171m5w,999 +transformers/models/unispeech/__pycache__/__init__.cpython-310.pyc,, +transformers/models/unispeech/__pycache__/configuration_unispeech.cpython-310.pyc,, +transformers/models/unispeech/__pycache__/modeling_unispeech.cpython-310.pyc,, +transformers/models/unispeech/__pycache__/modular_unispeech.cpython-310.pyc,, +transformers/models/unispeech/configuration_unispeech.py,sha256=LZqwCBTds8aX7mOoq36V3YDHQwJK-23Fan-NkjZBN3U,17537 +transformers/models/unispeech/modeling_unispeech.py,sha256=iMJCtj0DKy9e26Ni_tSrfSsuq3V8CH8PpTmN15smTeM,60321 +transformers/models/unispeech/modular_unispeech.py,sha256=wNjFfLNqzRlBZIyix0kboaYB3v6K9dw6ehxgaWrHzbk,17560 +transformers/models/unispeech_sat/__init__.py,sha256=P9lCzMg01s4Gj_Pb8t1l36MRAeoOcxUa4d7dbQSe9N4,1007 +transformers/models/unispeech_sat/__pycache__/__init__.cpython-310.pyc,, +transformers/models/unispeech_sat/__pycache__/configuration_unispeech_sat.cpython-310.pyc,, +transformers/models/unispeech_sat/__pycache__/modeling_unispeech_sat.cpython-310.pyc,, +transformers/models/unispeech_sat/__pycache__/modular_unispeech_sat.cpython-310.pyc,, +transformers/models/unispeech_sat/configuration_unispeech_sat.py,sha256=SC2ZitixAwMYer5jGpTlzIDEn11IE2nADDkej4CgP-Q,18882 +transformers/models/unispeech_sat/modeling_unispeech_sat.py,sha256=JQaHK72GXF-dVUb8_j3rgRon3lBPLOqTuCE_uCuip58,73361 +transformers/models/unispeech_sat/modular_unispeech_sat.py,sha256=jwX-Ao2iQUw1uHjJRp3TZSmEl7-xLizFsAMXXhznjtU,17953 +transformers/models/univnet/__init__.py,sha256=hfHyxyKGEfd58p1fUSA3IxK2q6JkVatkGceVaoKuODk,1041 +transformers/models/univnet/__pycache__/__init__.cpython-310.pyc,, +transformers/models/univnet/__pycache__/configuration_univnet.cpython-310.pyc,, +transformers/models/univnet/__pycache__/feature_extraction_univnet.cpython-310.pyc,, +transformers/models/univnet/__pycache__/modeling_univnet.cpython-310.pyc,, +transformers/models/univnet/configuration_univnet.py,sha256=0iphUNQuhWX9ttAp8lQ0LC8ZnqRSn22vuQGlSGYWSsE,6758 +transformers/models/univnet/feature_extraction_univnet.py,sha256=fLIbEVY2ItwXSTfwkmqZxC1obyHtDaWIXzJqHACsmK0,22748 +transformers/models/univnet/modeling_univnet.py,sha256=q4CqsvHDQXsxM2jruUgwj7amtCjZrTabuGY-6xN6OYI,25423 +transformers/models/upernet/__init__.py,sha256=Wq3u7yXJul5PLmjalxKgx451sa_WuSXbEM45bZsRv3E,995 +transformers/models/upernet/__pycache__/__init__.cpython-310.pyc,, +transformers/models/upernet/__pycache__/configuration_upernet.cpython-310.pyc,, +transformers/models/upernet/__pycache__/modeling_upernet.cpython-310.pyc,, +transformers/models/upernet/configuration_upernet.py,sha256=_LBTSTQqF4fT4zIYAjUmaEndsOJE-eRN8n_a8aADXIU,4899 +transformers/models/upernet/modeling_upernet.py,sha256=WYFJ_TRxtUbxMoZsLFmCZM1P_K-ZjpveuFvHNd0FUOM,14155 +transformers/models/vaultgemma/__init__.py,sha256=d-2ptvRau3FlBamhyOMQnMVX3tvL-dQnfm4CyQJBBRA,1002 +transformers/models/vaultgemma/__pycache__/__init__.cpython-310.pyc,, +transformers/models/vaultgemma/__pycache__/configuration_vaultgemma.cpython-310.pyc,, +transformers/models/vaultgemma/__pycache__/modeling_vaultgemma.cpython-310.pyc,, +transformers/models/vaultgemma/__pycache__/modular_vaultgemma.cpython-310.pyc,, +transformers/models/vaultgemma/configuration_vaultgemma.py,sha256=m_nYTjtBqadFJnfRb69c2tSYEHutjR9O_iwJiqwLH2A,10319 +transformers/models/vaultgemma/modeling_vaultgemma.py,sha256=r6rgq7fBZ7pM1DoXCTrtwOeflt3rXeb-ubYp7DQqMnk,23836 +transformers/models/vaultgemma/modular_vaultgemma.py,sha256=qbMzO6j8S0MufGdH7MV4pgx_h6qzMOgtpYrwiHpqoTw,10624 +transformers/models/vibevoice_acoustic_tokenizer/__init__.py,sha256=B8iNqUEKPRSTqVHk_x8cIYdTtZJz9CyFb9CXxPs2xbQ,1104 +transformers/models/vibevoice_acoustic_tokenizer/__pycache__/__init__.cpython-310.pyc,, +transformers/models/vibevoice_acoustic_tokenizer/__pycache__/configuration_vibevoice_acoustic_tokenizer.cpython-310.pyc,, +transformers/models/vibevoice_acoustic_tokenizer/__pycache__/feature_extraction_vibevoice_acoustic_tokenizer.cpython-310.pyc,, +transformers/models/vibevoice_acoustic_tokenizer/__pycache__/modeling_vibevoice_acoustic_tokenizer.cpython-310.pyc,, +transformers/models/vibevoice_acoustic_tokenizer/__pycache__/modular_vibevoice_acoustic_tokenizer.cpython-310.pyc,, +transformers/models/vibevoice_acoustic_tokenizer/configuration_vibevoice_acoustic_tokenizer.py,sha256=kb26dyw4MQ8F3FCWK18laPnot8XHrR4TglV-_8_BAas,6382 +transformers/models/vibevoice_acoustic_tokenizer/feature_extraction_vibevoice_acoustic_tokenizer.py,sha256=UAIkeW8pchBTGC16MjmhIXo5SwMA9BJF_7EQi0aa28o,6514 +transformers/models/vibevoice_acoustic_tokenizer/modeling_vibevoice_acoustic_tokenizer.py,sha256=9TE58L9Sqq9wkC9UsF03OTjWWF6PLORXBMPrayyng24,24428 +transformers/models/vibevoice_acoustic_tokenizer/modular_vibevoice_acoustic_tokenizer.py,sha256=LcfGNX7OdwKLfh8fh5pHM1lxDnCAMqdRL4fHKk1SJnU,20686 +transformers/models/vibevoice_asr/__init__.py,sha256=aOGnTphzUJ3gePowLi9_HKYbbg__u4OKuaWA8vQk0Bk,1071 +transformers/models/vibevoice_asr/__pycache__/__init__.cpython-310.pyc,, +transformers/models/vibevoice_asr/__pycache__/configuration_vibevoice_asr.cpython-310.pyc,, +transformers/models/vibevoice_asr/__pycache__/modeling_vibevoice_asr.cpython-310.pyc,, +transformers/models/vibevoice_asr/__pycache__/modular_vibevoice_asr.cpython-310.pyc,, +transformers/models/vibevoice_asr/__pycache__/processing_vibevoice_asr.cpython-310.pyc,, +transformers/models/vibevoice_asr/configuration_vibevoice_asr.py,sha256=K2OzKrKW-kKt9jn6q94AvcZwhntHyIMUHvb2AJlVV2A,6851 +transformers/models/vibevoice_asr/modeling_vibevoice_asr.py,sha256=JUQ4DupVaOKdy0-rW0dAVZuIuKEmkVDUiA2GpRHae8k,19743 +transformers/models/vibevoice_asr/modular_vibevoice_asr.py,sha256=DcKH-PEG7YzYrCE4ux56VWXGn8bp5Smpe5rQjCeFKNs,16523 +transformers/models/vibevoice_asr/processing_vibevoice_asr.py,sha256=kCt43_IelZN7nGrGk_F2tZxkqNVc-T-BFqeCgY-mc1o,15851 +transformers/models/video_llama_3/__init__.py,sha256=_ZgoZnMTkVXzGnu_xWzcfmccT80nN3Sa4OxLA28LNag,1206 +transformers/models/video_llama_3/__pycache__/__init__.cpython-310.pyc,, +transformers/models/video_llama_3/__pycache__/configuration_video_llama_3.cpython-310.pyc,, +transformers/models/video_llama_3/__pycache__/image_processing_video_llama_3.cpython-310.pyc,, +transformers/models/video_llama_3/__pycache__/image_processing_video_llama_3_fast.cpython-310.pyc,, +transformers/models/video_llama_3/__pycache__/modeling_video_llama_3.cpython-310.pyc,, +transformers/models/video_llama_3/__pycache__/modular_video_llama_3.cpython-310.pyc,, +transformers/models/video_llama_3/__pycache__/processing_video_llama_3.cpython-310.pyc,, +transformers/models/video_llama_3/__pycache__/video_processing_video_llama_3.cpython-310.pyc,, +transformers/models/video_llama_3/configuration_video_llama_3.py,sha256=P-US42nX6b3WpAcC0lliGTRr8cNs1PRu1TrHGmdmV3I,7275 +transformers/models/video_llama_3/image_processing_video_llama_3.py,sha256=D5i-wlJ9KeRdFbMvfI3TWJ4muZK89Th2cwv9fWZdwYE,25849 +transformers/models/video_llama_3/image_processing_video_llama_3_fast.py,sha256=5NLagvdYnBy3U5UBwZV3YlBsV1k4s1vpgYQx4FFpvy0,12604 +transformers/models/video_llama_3/modeling_video_llama_3.py,sha256=nhMHtc04M1XwDlCgsKzzR6aQNYJ8ls3UHd036w6q-j0,50324 +transformers/models/video_llama_3/modular_video_llama_3.py,sha256=6Qdd8KXYrdHyFFryr9338gLFFPuItUWTYx1gaJQ4OGs,74979 +transformers/models/video_llama_3/processing_video_llama_3.py,sha256=zT1u8r04XH_adGNK3aBx2LdTWLAy8M_qT7FdrRfTgPU,11784 +transformers/models/video_llama_3/video_processing_video_llama_3.py,sha256=441j-z0RU63L2yt3CtkgpZdMgZMxUeS7Birk9ctCaGU,18414 +transformers/models/video_llava/__init__.py,sha256=bsLGp1WBBO_AvNVRxzOn5k7OYQIbX9SqFhESd24FImc,1093 +transformers/models/video_llava/__pycache__/__init__.cpython-310.pyc,, +transformers/models/video_llava/__pycache__/configuration_video_llava.cpython-310.pyc,, +transformers/models/video_llava/__pycache__/image_processing_video_llava.cpython-310.pyc,, +transformers/models/video_llava/__pycache__/modeling_video_llava.cpython-310.pyc,, +transformers/models/video_llava/__pycache__/processing_video_llava.cpython-310.pyc,, +transformers/models/video_llava/__pycache__/video_processing_video_llava.cpython-310.pyc,, +transformers/models/video_llava/configuration_video_llava.py,sha256=2XkFxJsJN5KbhXlWAKvVffR_kU72jXpCY8YVVzxDrtY,6639 +transformers/models/video_llava/image_processing_video_llava.py,sha256=FiopnKA5a9Sa0ZGfXaYout_cemM5oG1IaeM70dSB9H8,16825 +transformers/models/video_llava/modeling_video_llava.py,sha256=JrLEl_pzngqU0JSiJPsh8yxJDk4bGR0O90_8f71AS-M,29727 +transformers/models/video_llava/processing_video_llava.py,sha256=U2IjhsbigW-5CEJIxc0rtsL28IPWiL8SiG57K3JOeD0,7450 +transformers/models/video_llava/video_processing_video_llava.py,sha256=Aomg9TFiRNtufNGT00RZArhv46Dl6FBl3tc3VQZosjg,1320 +transformers/models/videomae/__init__.py,sha256=4vBgjF7k3KHmqe9T6mBDxpHZu6VPh6zSFhhhMVdvVjM,1134 +transformers/models/videomae/__pycache__/__init__.cpython-310.pyc,, +transformers/models/videomae/__pycache__/configuration_videomae.cpython-310.pyc,, +transformers/models/videomae/__pycache__/image_processing_videomae.cpython-310.pyc,, +transformers/models/videomae/__pycache__/modeling_videomae.cpython-310.pyc,, +transformers/models/videomae/__pycache__/video_processing_videomae.cpython-310.pyc,, +transformers/models/videomae/configuration_videomae.py,sha256=oNe2fBtG8RrjJdRtpT733emfi6_sqizqEezDu1aFF30,6585 +transformers/models/videomae/image_processing_videomae.py,sha256=aQ_ba2hiuK-wugP1yDEUcPBP3yASaE6FviRbOlVnL9A,16317 +transformers/models/videomae/modeling_videomae.py,sha256=7xvzAn1TlYBHbh1mRalXxJfJ6SuRKZ_mqU2iC7JPFpw,30969 +transformers/models/videomae/video_processing_videomae.py,sha256=VivwNTSmRKdflwjtm5LTvJFPoQXeY-YmtxFlpR-6c70,1582 +transformers/models/vilt/__init__.py,sha256=efaZSTGsk3QhZmBrc6F29q55LkC_1Vb8fNC0MY4881Q,1154 +transformers/models/vilt/__pycache__/__init__.cpython-310.pyc,, +transformers/models/vilt/__pycache__/configuration_vilt.cpython-310.pyc,, +transformers/models/vilt/__pycache__/image_processing_vilt.cpython-310.pyc,, +transformers/models/vilt/__pycache__/image_processing_vilt_fast.cpython-310.pyc,, +transformers/models/vilt/__pycache__/modeling_vilt.cpython-310.pyc,, +transformers/models/vilt/__pycache__/processing_vilt.cpython-310.pyc,, +transformers/models/vilt/configuration_vilt.py,sha256=sdn1ntgN8l40Ll05QCzp4TnL4xNZ2lBjSyuUSvlkF2Y,6935 +transformers/models/vilt/image_processing_vilt.py,sha256=uuBNA4Ij16WdBYWEOT6ekjRrWMCbGQHifyMcOa9Th5Y,22082 +transformers/models/vilt/image_processing_vilt_fast.py,sha256=Qu8nTrv7t32CqyJv4qg6J5bOq0ocKZOSU1tUZRGmdeQ,9012 +transformers/models/vilt/modeling_vilt.py,sha256=NkGg6_7egh3PQqujl0zrFcqSO0WcdMsCT-D54xNsP3w,54108 +transformers/models/vilt/processing_vilt.py,sha256=ENfJmMX9MAGot1QsNiYnsyDF48iIXqs5eH4XnM74paM,1408 +transformers/models/vipllava/__init__.py,sha256=HJ5mZUNdt_bmaC9l-GycD7mVT2r1oN15prmnlBtz6oA,997 +transformers/models/vipllava/__pycache__/__init__.cpython-310.pyc,, +transformers/models/vipllava/__pycache__/configuration_vipllava.cpython-310.pyc,, +transformers/models/vipllava/__pycache__/modeling_vipllava.cpython-310.pyc,, +transformers/models/vipllava/__pycache__/modular_vipllava.cpython-310.pyc,, +transformers/models/vipllava/configuration_vipllava.py,sha256=mY0TB-AOOh6-CFuvHynzixyZbcSCGvjn5dL1bRYLuns,5240 +transformers/models/vipllava/modeling_vipllava.py,sha256=-ArzAqY1EV4YivKAfIATWTyuQ8BUF9u5MhujPv78XeE,21165 +transformers/models/vipllava/modular_vipllava.py,sha256=euKVJnmoi8lWZrp8w9dzzjG5XNlIFo4yOS0HsnkTi78,13185 +transformers/models/vision_encoder_decoder/__init__.py,sha256=noRw3j3TsUX_pmu-lPHZtprgJIRoohYtpDl-Ebwbfgo,1025 +transformers/models/vision_encoder_decoder/__pycache__/__init__.cpython-310.pyc,, +transformers/models/vision_encoder_decoder/__pycache__/configuration_vision_encoder_decoder.cpython-310.pyc,, +transformers/models/vision_encoder_decoder/__pycache__/modeling_vision_encoder_decoder.cpython-310.pyc,, +transformers/models/vision_encoder_decoder/configuration_vision_encoder_decoder.py,sha256=WJu-LiZyMKsJwyRUJqXdI1cjTUptPZm-VzGoVkxyC1Y,4685 +transformers/models/vision_encoder_decoder/modeling_vision_encoder_decoder.py,sha256=MVaGC4LNRR35vVLGfIVZERmGYoUJRSTPNk4Wg6jbxEI,22010 +transformers/models/vision_text_dual_encoder/__init__.py,sha256=j-CUSG80TkFAaWDzRmQSBgARhrzpHUaKWQUPJ2ZdvIw,1084 +transformers/models/vision_text_dual_encoder/__pycache__/__init__.cpython-310.pyc,, +transformers/models/vision_text_dual_encoder/__pycache__/configuration_vision_text_dual_encoder.cpython-310.pyc,, +transformers/models/vision_text_dual_encoder/__pycache__/modeling_vision_text_dual_encoder.cpython-310.pyc,, +transformers/models/vision_text_dual_encoder/__pycache__/processing_vision_text_dual_encoder.cpython-310.pyc,, +transformers/models/vision_text_dual_encoder/configuration_vision_text_dual_encoder.py,sha256=1V5owZl17CHivX7Oc6OdkumaYW5D--y_fEtIisM36Iw,5008 +transformers/models/vision_text_dual_encoder/modeling_vision_text_dual_encoder.py,sha256=mA1K6uh-pINRo2u7uu8pU2dPjAEMDBEeFIf9ti4xU9Q,17553 +transformers/models/vision_text_dual_encoder/processing_vision_text_dual_encoder.py,sha256=2EGdP2Ram632GK8HbvjxpKZGwAEDGke9vIZfccaI2hw,1082 +transformers/models/visual_bert/__init__.py,sha256=zZFHfkE7OUMZUwYvB7v4ZIBXVUW9Mboqoa1QdTQURWM,1003 +transformers/models/visual_bert/__pycache__/__init__.cpython-310.pyc,, +transformers/models/visual_bert/__pycache__/configuration_visual_bert.cpython-310.pyc,, +transformers/models/visual_bert/__pycache__/modeling_visual_bert.cpython-310.pyc,, +transformers/models/visual_bert/configuration_visual_bert.py,sha256=5D5Eb3C87JxZ2ZJqBZxYCBp_GKVFCawyNb6Dg-ccy34,6883 +transformers/models/visual_bert/modeling_visual_bert.py,sha256=E_BfiMocB941Cb0FrSlkrmphfHw5MiZQkF1EIVF32oc,67332 +transformers/models/vit/__init__.py,sha256=893K3i6fsEym2vyvQFpE2_yfZcCxo4C3xf7vr8vY38I,1114 +transformers/models/vit/__pycache__/__init__.cpython-310.pyc,, +transformers/models/vit/__pycache__/configuration_vit.cpython-310.pyc,, +transformers/models/vit/__pycache__/image_processing_vit.cpython-310.pyc,, +transformers/models/vit/__pycache__/image_processing_vit_fast.cpython-310.pyc,, +transformers/models/vit/__pycache__/modeling_vit.cpython-310.pyc,, +transformers/models/vit/configuration_vit.py,sha256=Xd0pzqtYLPT22b8Y6DbR2ZC1apPmnkaiA69l3QAoyd8,5541 +transformers/models/vit/image_processing_vit.py,sha256=ELRtmsGTmMWhjxDkEQJytrj8CYdKD_ER-LHVWFyh1sY,14034 +transformers/models/vit/image_processing_vit_fast.py,sha256=NlrrjSsiM4hGTeVpxknZ_aX-8tKPkkHVdcIy24gkSGY,1222 +transformers/models/vit/modeling_vit.py,sha256=NMXRaJr9fgACmQowBWXgJ4rIemRjTmMbYM658wrf6Z4,26040 +transformers/models/vit_mae/__init__.py,sha256=yrtk-59bpQGketwQFpVmON5rOe7GOctf8NJJZH09WBk,995 +transformers/models/vit_mae/__pycache__/__init__.cpython-310.pyc,, +transformers/models/vit_mae/__pycache__/configuration_vit_mae.cpython-310.pyc,, +transformers/models/vit_mae/__pycache__/modeling_vit_mae.cpython-310.pyc,, +transformers/models/vit_mae/configuration_vit_mae.py,sha256=ay-3DSdGyJ1U26wwpyxJzmkucUSyJvx0KPvDOXE7isI,6357 +transformers/models/vit_mae/modeling_vit_mae.py,sha256=IcZxjkyhCrSdfEEpko7d3lQTn7BNtKUjmCtcXN9B-Vs,38305 +transformers/models/vit_msn/__init__.py,sha256=Y1g56VRSNr-PxS-g4Cp2IlRR5M9CiaFGlhAQXwszGHo,995 +transformers/models/vit_msn/__pycache__/__init__.cpython-310.pyc,, +transformers/models/vit_msn/__pycache__/configuration_vit_msn.cpython-310.pyc,, +transformers/models/vit_msn/__pycache__/modeling_vit_msn.cpython-310.pyc,, +transformers/models/vit_msn/configuration_vit_msn.py,sha256=khhczZQ1gekgE-vK4urtfVDS7X8k1FSIkrF9iQpEJKk,4849 +transformers/models/vit_msn/modeling_vit_msn.py,sha256=aV1hAjEYDWvU40Vn74JAVTfgy_4NfuT_uUH2APSLjFw,21855 +transformers/models/vitdet/__init__.py,sha256=13LNGZwvKK3tBrQWVs43rQbxbgqvxLfnM0uMqomHqhM,993 +transformers/models/vitdet/__pycache__/__init__.cpython-310.pyc,, +transformers/models/vitdet/__pycache__/configuration_vitdet.cpython-310.pyc,, +transformers/models/vitdet/__pycache__/modeling_vitdet.cpython-310.pyc,, +transformers/models/vitdet/configuration_vitdet.py,sha256=HMqE2GjxVI6h2LmUtNyCjAJ2Z0b28vrinUc3WkIXmJM,7381 +transformers/models/vitdet/modeling_vitdet.py,sha256=OKauot-xaNBXoQzUezJ6r1hXsjnD5L-FPBZAYGuZ8bE,29796 +transformers/models/vitmatte/__init__.py,sha256=al6dWrth9LhRLjmVZrxSi0SRcMMUH_UNpMmR5nwflSc,1092 +transformers/models/vitmatte/__pycache__/__init__.cpython-310.pyc,, +transformers/models/vitmatte/__pycache__/configuration_vitmatte.cpython-310.pyc,, +transformers/models/vitmatte/__pycache__/image_processing_vitmatte.cpython-310.pyc,, +transformers/models/vitmatte/__pycache__/image_processing_vitmatte_fast.cpython-310.pyc,, +transformers/models/vitmatte/__pycache__/modeling_vitmatte.cpython-310.pyc,, +transformers/models/vitmatte/configuration_vitmatte.py,sha256=CMuXb_j9HzwOX8RRNYgFdRPC3HJH_XCj6t5hDDrxJ3g,3980 +transformers/models/vitmatte/image_processing_vitmatte.py,sha256=gN5ooEP9nQy_9jLGTzXBV8lNoHPejYEwqpv8k6QZYJ4,13203 +transformers/models/vitmatte/image_processing_vitmatte_fast.py,sha256=R3_ZNGx3EvNhdOx6hM4Pya84WmZDI9_t5L_Hw5Xipuc,5831 +transformers/models/vitmatte/modeling_vitmatte.py,sha256=ihMN7L4Um0xNQ8Qa2gT7icA7qnxtIwFaWqUKaZLQdf0,10873 +transformers/models/vitpose/__init__.py,sha256=Nt5JL9KutJ_ut6MLlr6oUDeyOYIeZY0MtKZsePTm1Ps,1088 +transformers/models/vitpose/__pycache__/__init__.cpython-310.pyc,, +transformers/models/vitpose/__pycache__/configuration_vitpose.cpython-310.pyc,, +transformers/models/vitpose/__pycache__/image_processing_vitpose.cpython-310.pyc,, +transformers/models/vitpose/__pycache__/image_processing_vitpose_fast.cpython-310.pyc,, +transformers/models/vitpose/__pycache__/modeling_vitpose.cpython-310.pyc,, +transformers/models/vitpose/configuration_vitpose.py,sha256=r-B273YF3MuE6PgaP1_w3vAWBH7H6zPKY520c2H79eI,3593 +transformers/models/vitpose/image_processing_vitpose.py,sha256=nKhCbAC54i_dJs5X_sMi5lqx6zMDQXmWq1dcSYlxl7w,29828 +transformers/models/vitpose/image_processing_vitpose_fast.py,sha256=RkjZucsP9n1ao2Gm_GBGYUqpcuYsNuzsZ5UtfH4ynTs,11811 +transformers/models/vitpose/modeling_vitpose.py,sha256=liTbils_xmJEsZNycLdv1LNrnG8AczLQ2-UKaCqgra4,11513 +transformers/models/vitpose_backbone/__init__.py,sha256=W5IjP47Ykg5KRs8S9ztAbtfQ__n6sbJUZG4UDIGdGmA,577 +transformers/models/vitpose_backbone/__pycache__/__init__.cpython-310.pyc,, +transformers/models/vitpose_backbone/__pycache__/configuration_vitpose_backbone.cpython-310.pyc,, +transformers/models/vitpose_backbone/__pycache__/modeling_vitpose_backbone.cpython-310.pyc,, +transformers/models/vitpose_backbone/configuration_vitpose_backbone.py,sha256=0v3rIoNkltmhh4CVO4VyvnwuPCo_sHF-tQrYcXx939g,6491 +transformers/models/vitpose_backbone/modeling_vitpose_backbone.py,sha256=2ENVsYtgFLy4cECxoglZ9N1N2kUqWAwehopfNty8GfI,17329 +transformers/models/vits/__init__.py,sha256=7baZcqGvFlYQxAl721XtMptMZKkzvBOa2ttyOhqhUtk,1026 +transformers/models/vits/__pycache__/__init__.cpython-310.pyc,, +transformers/models/vits/__pycache__/configuration_vits.cpython-310.pyc,, +transformers/models/vits/__pycache__/modeling_vits.cpython-310.pyc,, +transformers/models/vits/__pycache__/tokenization_vits.cpython-310.pyc,, +transformers/models/vits/configuration_vits.py,sha256=KSF7D__c3W40_ilsxib_LWSq-2OgotSnU9F38vQJliE,14017 +transformers/models/vits/modeling_vits.py,sha256=49zd1M4DwzHoTxkvILFleZZaxrldR93olQnAQIuPVgk,61626 +transformers/models/vits/tokenization_vits.py,sha256=0TjYs-5TIx7K5ujDYCYz-bEl2SEOBrtM6of2chEqXaU,9402 +transformers/models/vivit/__init__.py,sha256=LT2FipIBdB69s9UY4viyuB5q2e0v3bCwtQMiOEOj2xg,1033 +transformers/models/vivit/__pycache__/__init__.cpython-310.pyc,, +transformers/models/vivit/__pycache__/configuration_vivit.cpython-310.pyc,, +transformers/models/vivit/__pycache__/image_processing_vivit.cpython-310.pyc,, +transformers/models/vivit/__pycache__/modeling_vivit.cpython-310.pyc,, +transformers/models/vivit/configuration_vivit.py,sha256=SKyPstXxyrqMtQlhh73_O14wIT44ldCRUTQqEdsYBXk,5127 +transformers/models/vivit/image_processing_vivit.py,sha256=Zxlzx1tUw7QYjoRpJkMIvKCUz2fU3EG8jv41llp3qLs,18761 +transformers/models/vivit/modeling_vivit.py,sha256=KtfPe30MYR86PMyFltxkIJ5kBnoHYmpIA2mM4HZvQ3s,25907 +transformers/models/vjepa2/__init__.py,sha256=VpyCyuPpmmGMFjOOK4dG0E14Kb_wv5vn3CWyJ7dG7zk,1041 +transformers/models/vjepa2/__pycache__/__init__.cpython-310.pyc,, +transformers/models/vjepa2/__pycache__/configuration_vjepa2.cpython-310.pyc,, +transformers/models/vjepa2/__pycache__/modeling_vjepa2.cpython-310.pyc,, +transformers/models/vjepa2/__pycache__/video_processing_vjepa2.cpython-310.pyc,, +transformers/models/vjepa2/configuration_vjepa2.py,sha256=BHXFNbz6svFGBrMsjuKirj-zeBCEo0IltvmxdNfxdio,7040 +transformers/models/vjepa2/modeling_vjepa2.py,sha256=3QZYY1cAwGyOzP7Gj8GwFSXQNYg7fGFLUk4XALmfZKg,44788 +transformers/models/vjepa2/video_processing_vjepa2.py,sha256=EAhWf1LAr8WF5cu_QNG34Wa6gDnDP__jyGdrZ-bRpFM,1739 +transformers/models/voxtral/__init__.py,sha256=79Rf85nRl4CR_MQPk1x12SviCaAnMITesrFTeeX4F8g,1038 +transformers/models/voxtral/__pycache__/__init__.cpython-310.pyc,, +transformers/models/voxtral/__pycache__/configuration_voxtral.cpython-310.pyc,, +transformers/models/voxtral/__pycache__/modeling_voxtral.cpython-310.pyc,, +transformers/models/voxtral/__pycache__/modular_voxtral.cpython-310.pyc,, +transformers/models/voxtral/__pycache__/processing_voxtral.cpython-310.pyc,, +transformers/models/voxtral/configuration_voxtral.py,sha256=dmvanRSOXmaRgCE9gsOni4Fm8skT0Ieqh-fnc38nesU,8410 +transformers/models/voxtral/modeling_voxtral.py,sha256=9emuzSpceFJPZ1hfJr6hKN4T2dGDC-i0xzxPIZKDp08,21800 +transformers/models/voxtral/modular_voxtral.py,sha256=jJT_Q0ZrcphCFtNzyNkXZt8rMWPG4fKMD9GG7CViQQY,11780 +transformers/models/voxtral/processing_voxtral.py,sha256=krW9bnpkotXWQ4crQ9A2vYIp0mu_-EuMAzBwys_IomE,17486 +transformers/models/voxtral_realtime/__init__.py,sha256=7xSSVk6n6J-niLQixx6mUsLLsaNU7PEGwibIyIiGBhk,1065 +transformers/models/voxtral_realtime/__pycache__/__init__.cpython-310.pyc,, +transformers/models/voxtral_realtime/__pycache__/configuration_voxtral_realtime.cpython-310.pyc,, +transformers/models/voxtral_realtime/__pycache__/feature_extraction_voxtral_realtime.cpython-310.pyc,, +transformers/models/voxtral_realtime/__pycache__/modeling_voxtral_realtime.cpython-310.pyc,, +transformers/models/voxtral_realtime/__pycache__/modular_voxtral_realtime.cpython-310.pyc,, +transformers/models/voxtral_realtime/__pycache__/processing_voxtral_realtime.cpython-310.pyc,, +transformers/models/voxtral_realtime/configuration_voxtral_realtime.py,sha256=ejlcGFCWWXNL-1JXehGT2EKljwrA0Rga8rqk7jNo6YQ,10625 +transformers/models/voxtral_realtime/feature_extraction_voxtral_realtime.py,sha256=9CQ7XAjgXJ1WWpu3wSPzQGFnJtnyBddt8s6fdHhLR5M,11565 +transformers/models/voxtral_realtime/modeling_voxtral_realtime.py,sha256=D_BIrCvzLb_4zWDQk5NmwsyN2qKcK3YofLC_oa7WPPM,57471 +transformers/models/voxtral_realtime/modular_voxtral_realtime.py,sha256=xNNcW56SVbEYI-2lHacEBd7yNe8ked5cVxYAhAZR7Ns,36935 +transformers/models/voxtral_realtime/processing_voxtral_realtime.py,sha256=3kk8ePc247IEX39a_-6jda6BtDm38lEYS0r6SjOngKc,9294 +transformers/models/wav2vec2/__init__.py,sha256=jc_01S-UEuKOfO2DY2mzogAoCZnLvrTlS_yDV9SQW5w,1124 +transformers/models/wav2vec2/__pycache__/__init__.cpython-310.pyc,, +transformers/models/wav2vec2/__pycache__/configuration_wav2vec2.cpython-310.pyc,, +transformers/models/wav2vec2/__pycache__/feature_extraction_wav2vec2.cpython-310.pyc,, +transformers/models/wav2vec2/__pycache__/modeling_wav2vec2.cpython-310.pyc,, +transformers/models/wav2vec2/__pycache__/processing_wav2vec2.cpython-310.pyc,, +transformers/models/wav2vec2/__pycache__/tokenization_wav2vec2.cpython-310.pyc,, +transformers/models/wav2vec2/configuration_wav2vec2.py,sha256=JObEyzEq8Bz2TjOg89TzPSrNKJA4R5ZMo6ILwnVEMi0,20104 +transformers/models/wav2vec2/feature_extraction_wav2vec2.py,sha256=5emguvcHFv7lA_T2anphMSoTK-mJstfiZJ4FfMvvosw,11461 +transformers/models/wav2vec2/modeling_wav2vec2.py,sha256=Y6WlFXCIvn1cen13qP0JFzTr99IGgJ_Dj-Tei1Yc6fg,92137 +transformers/models/wav2vec2/processing_wav2vec2.py,sha256=la2vToOYyj1yVw66MpJdzZZO07ACfvmr_x_SRUqW1Vk,4105 +transformers/models/wav2vec2/tokenization_wav2vec2.py,sha256=tPj4CDjkYrxdd7OZiqUAh5vczpUXeSI8lM4Sb3_6aPI,28090 +transformers/models/wav2vec2_bert/__init__.py,sha256=DL010VL3ZV3lAugPH-BOTNSgIedotOEaoy8iHo0sC1Q,1051 +transformers/models/wav2vec2_bert/__pycache__/__init__.cpython-310.pyc,, +transformers/models/wav2vec2_bert/__pycache__/configuration_wav2vec2_bert.cpython-310.pyc,, +transformers/models/wav2vec2_bert/__pycache__/modeling_wav2vec2_bert.cpython-310.pyc,, +transformers/models/wav2vec2_bert/__pycache__/modular_wav2vec2_bert.cpython-310.pyc,, +transformers/models/wav2vec2_bert/__pycache__/processing_wav2vec2_bert.cpython-310.pyc,, +transformers/models/wav2vec2_bert/configuration_wav2vec2_bert.py,sha256=PYiTbIIqa9txnY-m4ChXgC1o1N1NbL2mz48cG4zUYrY,18169 +transformers/models/wav2vec2_bert/modeling_wav2vec2_bert.py,sha256=JrNsh-nwjTEcuoRxKzlJA6SDzipS1cEpwFFm7_k6ivU,66620 +transformers/models/wav2vec2_bert/modular_wav2vec2_bert.py,sha256=DQCNV1V9YKC7pwntFdeAFAvaMDJKyAD8h0vYDy8ofvo,45274 +transformers/models/wav2vec2_bert/processing_wav2vec2_bert.py,sha256=EVdhaO29UKL23HTimd5t0a1wTW6O9Vi5WCNGC_HZcsQ,4230 +transformers/models/wav2vec2_conformer/__init__.py,sha256=JBpapW8VF3yck4Bk29xKyUiQZqB_CXLSYtYxXGXAu2Q,1017 +transformers/models/wav2vec2_conformer/__pycache__/__init__.cpython-310.pyc,, +transformers/models/wav2vec2_conformer/__pycache__/configuration_wav2vec2_conformer.cpython-310.pyc,, +transformers/models/wav2vec2_conformer/__pycache__/modeling_wav2vec2_conformer.cpython-310.pyc,, +transformers/models/wav2vec2_conformer/__pycache__/modular_wav2vec2_conformer.cpython-310.pyc,, +transformers/models/wav2vec2_conformer/configuration_wav2vec2_conformer.py,sha256=26ATO-ZerENQo9pkDzaHX0wsdOYkc40DYjsvQzsDkks,20965 +transformers/models/wav2vec2_conformer/modeling_wav2vec2_conformer.py,sha256=zHz1I5c3WzcmTuiOJ5Q9KTNojpNJQacZ0MXw1S4PGE8,85961 +transformers/models/wav2vec2_conformer/modular_wav2vec2_conformer.py,sha256=0_Z45el2aM6rMUuGm7y0Kbt48c7bWSRAe12MY0H6_V0,30722 +transformers/models/wav2vec2_phoneme/__init__.py,sha256=LV4FKcFYNt0GuJvfsUOwTYVFRVfuzUuclKRybFyN9lk,967 +transformers/models/wav2vec2_phoneme/__pycache__/__init__.cpython-310.pyc,, +transformers/models/wav2vec2_phoneme/__pycache__/tokenization_wav2vec2_phoneme.cpython-310.pyc,, +transformers/models/wav2vec2_phoneme/tokenization_wav2vec2_phoneme.py,sha256=vshAJq_PHEs5cZDkmFh_JdCwmVY81u_ouuoR5BJ050Y,22848 +transformers/models/wav2vec2_with_lm/__init__.py,sha256=yZKHsma85j7AMLB8g8uNXL5D_E5Gc3Vqe-D-V2W15oY,965 +transformers/models/wav2vec2_with_lm/__pycache__/__init__.cpython-310.pyc,, +transformers/models/wav2vec2_with_lm/__pycache__/processing_wav2vec2_with_lm.cpython-310.pyc,, +transformers/models/wav2vec2_with_lm/processing_wav2vec2_with_lm.py,sha256=WbCAA5CaEeQDUeuFb3HwX-rXVXLM346TuY-WABeQ4ew,27470 +transformers/models/wavlm/__init__.py,sha256=wYnYuOpw2e95lauqDbD7u3OC-Pez8yoRsrgExSh_WJQ,991 +transformers/models/wavlm/__pycache__/__init__.cpython-310.pyc,, +transformers/models/wavlm/__pycache__/configuration_wavlm.cpython-310.pyc,, +transformers/models/wavlm/__pycache__/modeling_wavlm.cpython-310.pyc,, +transformers/models/wavlm/__pycache__/modular_wavlm.cpython-310.pyc,, +transformers/models/wavlm/configuration_wavlm.py,sha256=IXCNe5s6e8qtPT3mYz8GPZGvi44cLV10HoRyIbYN9iQ,18615 +transformers/models/wavlm/modeling_wavlm.py,sha256=UBYbBST4r9kik-ipPCAWk5JPYwSBrQK-Bl7H6vJ-Ink,70091 +transformers/models/wavlm/modular_wavlm.py,sha256=B21bwv6Rp_FZJqyqgAKnaTw7QiD-bu6oR6xb9tLa20o,23192 +transformers/models/whisper/__init__.py,sha256=0PLlY8YXw9EADkK4hYK-E8ZaR_46sujYbzefSXOyQD4,1119 +transformers/models/whisper/__pycache__/__init__.cpython-310.pyc,, +transformers/models/whisper/__pycache__/configuration_whisper.cpython-310.pyc,, +transformers/models/whisper/__pycache__/english_normalizer.cpython-310.pyc,, +transformers/models/whisper/__pycache__/feature_extraction_whisper.cpython-310.pyc,, +transformers/models/whisper/__pycache__/generation_whisper.cpython-310.pyc,, +transformers/models/whisper/__pycache__/modeling_whisper.cpython-310.pyc,, +transformers/models/whisper/__pycache__/processing_whisper.cpython-310.pyc,, +transformers/models/whisper/__pycache__/tokenization_whisper.cpython-310.pyc,, +transformers/models/whisper/configuration_whisper.py,sha256=fiigvpF927vjWKHyzxB0jTGEn0axFYRU__cnqlxqAw8,14701 +transformers/models/whisper/english_normalizer.py,sha256=7MFEktX8DRMyrqNymmzcfExIrqcr7OrPy824R7bBrIM,22804 +transformers/models/whisper/feature_extraction_whisper.py,sha256=NKbYqtn38nSBliKSnk_3S-KhNvzWH4Dslo-eBcRcfzo,16784 +transformers/models/whisper/generation_whisper.py,sha256=8Zdxhb4QeloYS4jzDFajv673WjSQi8Uru_WW4TGGR28,109268 +transformers/models/whisper/modeling_whisper.py,sha256=Ic-rtngaJNp2TEmDaZF-xlDgLhA2JxJRrSDbSjTWpn4,67460 +transformers/models/whisper/processing_whisper.py,sha256=lAYDAlcpwO0fDd-zO-NzIChkdsIO1UgqvYBuY5oCMNY,2101 +transformers/models/whisper/tokenization_whisper.py,sha256=7Vze8guYd_WoB1FJJlnKsqKFPrIzGZjmxirNrv-JvSI,57861 +transformers/models/x_clip/__init__.py,sha256=ufjh6w7SNuNAUjAHp_MK3yRcrHm22-SfhZ0ZfbiXhGw,1030 +transformers/models/x_clip/__pycache__/__init__.cpython-310.pyc,, +transformers/models/x_clip/__pycache__/configuration_x_clip.cpython-310.pyc,, +transformers/models/x_clip/__pycache__/modeling_x_clip.cpython-310.pyc,, +transformers/models/x_clip/__pycache__/processing_x_clip.cpython-310.pyc,, +transformers/models/x_clip/configuration_x_clip.py,sha256=7i9gee-bCx-OjND7nCCyryBx8Csc3JyTkBzUTwKoOTk,18461 +transformers/models/x_clip/modeling_x_clip.py,sha256=UXcKBXIeYuE1xUNiON2dx-WnFmvIEYOWNtTb1UD3-2Q,60858 +transformers/models/x_clip/processing_x_clip.py,sha256=SVDxdPgQClodpKJCFo6xkwxO2O8j8WHPWqCsqGm-P9c,983 +transformers/models/xcodec/__init__.py,sha256=X16pTVB3loZ9OMnqHAaxInF1X5EOhxlmHjyxEvoqSWE,993 +transformers/models/xcodec/__pycache__/__init__.cpython-310.pyc,, +transformers/models/xcodec/__pycache__/configuration_xcodec.cpython-310.pyc,, +transformers/models/xcodec/__pycache__/modeling_xcodec.cpython-310.pyc,, +transformers/models/xcodec/configuration_xcodec.py,sha256=BwXYFi6iXXzhi5JPVRpLhk1YucGcPVsJuwqhVwPKQ50,7257 +transformers/models/xcodec/modeling_xcodec.py,sha256=IYhBG2keeP1-qKKqYbsmCojt6ODSdOharwmCMI8EIsc,25688 +transformers/models/xglm/__init__.py,sha256=9hKLQSFEPq3h3EOSrIJj7Hex0mtUKMx_OvplVlDmuOA,1026 +transformers/models/xglm/__pycache__/__init__.cpython-310.pyc,, +transformers/models/xglm/__pycache__/configuration_xglm.cpython-310.pyc,, +transformers/models/xglm/__pycache__/modeling_xglm.cpython-310.pyc,, +transformers/models/xglm/__pycache__/tokenization_xglm.cpython-310.pyc,, +transformers/models/xglm/configuration_xglm.py,sha256=whGH1vOMRrWXF-LSg8oqLgPGijgHtSpMHsZPNgPO97o,6009 +transformers/models/xglm/modeling_xglm.py,sha256=quhk7Vo_SOJ3Toj5s1OM3-b5pLrL9jnNlv0t3Dp0Jwg,29459 +transformers/models/xglm/tokenization_xglm.py,sha256=5uQZlWjFNi5fw3KeDqxoUfIujDsRHE6KJxUVtNSFfiM,5185 +transformers/models/xlm/__init__.py,sha256=P7Y7S7kLVM6Ww21JlaJYU7wmWagdieMfBoTycNZ5syU,1023 +transformers/models/xlm/__pycache__/__init__.cpython-310.pyc,, +transformers/models/xlm/__pycache__/configuration_xlm.cpython-310.pyc,, +transformers/models/xlm/__pycache__/modeling_xlm.cpython-310.pyc,, +transformers/models/xlm/__pycache__/tokenization_xlm.cpython-310.pyc,, +transformers/models/xlm/configuration_xlm.py,sha256=LmiXN-3jJR7BJdZoGBB9Z_J3LHv-A0w7qhQ_syMjGGE,10443 +transformers/models/xlm/modeling_xlm.py,sha256=YJ3R0xfwBy_ow-TgIOM-SI4QpU2rG1nqmbtLv9hNSsI,73560 +transformers/models/xlm/tokenization_xlm.py,sha256=g_yHWpJ34iTTN0oOsAzoGgjuWrygv-PLv6NDkxpTXBg,23357 +transformers/models/xlm_roberta/__init__.py,sha256=-FQ--ViqECUGBbnvEqwsodV_ZHis5j565quw2s3ZoU0,1096 +transformers/models/xlm_roberta/__pycache__/__init__.cpython-310.pyc,, +transformers/models/xlm_roberta/__pycache__/configuration_xlm_roberta.cpython-310.pyc,, +transformers/models/xlm_roberta/__pycache__/modeling_xlm_roberta.cpython-310.pyc,, +transformers/models/xlm_roberta/__pycache__/modular_xlm_roberta.cpython-310.pyc,, +transformers/models/xlm_roberta/__pycache__/tokenization_xlm_roberta.cpython-310.pyc,, +transformers/models/xlm_roberta/configuration_xlm_roberta.py,sha256=a0tl8hMnZs2VgSSEN-bMuViqSKrGSMRkpjMLdZAx7zI,6322 +transformers/models/xlm_roberta/modeling_xlm_roberta.py,sha256=gfwlh3XIgJx9r_UXl-KtLm6iZ2r_wttq8V40wOComwc,54029 +transformers/models/xlm_roberta/modular_xlm_roberta.py,sha256=h5gMUNCgRlBoWixb5o4BiKEflVTDqer82zsnwl7Eg30,23214 +transformers/models/xlm_roberta/tokenization_xlm_roberta.py,sha256=i6wWn0MEPhKAGBwq8BeumibFuuHBsThxY8lVHZzZz8Y,4797 +transformers/models/xlm_roberta_xl/__init__.py,sha256=V0fXTKk2hQmf5dKogCJ0HSiRBxVX-rs7c414ZoZIh28,1009 +transformers/models/xlm_roberta_xl/__pycache__/__init__.cpython-310.pyc,, +transformers/models/xlm_roberta_xl/__pycache__/configuration_xlm_roberta_xl.cpython-310.pyc,, +transformers/models/xlm_roberta_xl/__pycache__/modeling_xlm_roberta_xl.cpython-310.pyc,, +transformers/models/xlm_roberta_xl/__pycache__/modular_xlm_roberta_xl.cpython-310.pyc,, +transformers/models/xlm_roberta_xl/configuration_xlm_roberta_xl.py,sha256=Fq9c2WPte7kt0LKYH8nrvlZk1vUAeuyzHEFB8lAnlc0,6089 +transformers/models/xlm_roberta_xl/modeling_xlm_roberta_xl.py,sha256=FEGXqjLixEkYNLXHBdY086vb12S_7CA2SrHIRJAI3xE,51859 +transformers/models/xlm_roberta_xl/modular_xlm_roberta_xl.py,sha256=ZL4yr29cAgieYO9nG4kXhM1G7S-3Yn16JhooPGmBCd4,29818 +transformers/models/xlnet/__init__.py,sha256=duiSzkjZEX4hcXiYQ6O49FLoa5UMuKtMahrF5QnDM_Y,1029 +transformers/models/xlnet/__pycache__/__init__.cpython-310.pyc,, +transformers/models/xlnet/__pycache__/configuration_xlnet.cpython-310.pyc,, +transformers/models/xlnet/__pycache__/modeling_xlnet.cpython-310.pyc,, +transformers/models/xlnet/__pycache__/tokenization_xlnet.cpython-310.pyc,, +transformers/models/xlnet/configuration_xlnet.py,sha256=qCFmK4bmLjyJmjUA-4dLDu1IO-MhbVjq7qxg4WI7YLk,10413 +transformers/models/xlnet/modeling_xlnet.py,sha256=D_dKyxANxcPNrfD8yfJUb0Gla2UWqV07zMJszQ7gECo,97569 +transformers/models/xlnet/tokenization_xlnet.py,sha256=Rrp8n_Gu1yofyNhWkgjpEb7Zs0Iz2kCecCJE1xFPqfM,7668 +transformers/models/xlstm/__init__.py,sha256=-Vfj7bUcDAD3TguoDgKW0zpzZ8KtOmnUNwSkvL6Df8k,1047 +transformers/models/xlstm/__pycache__/__init__.cpython-310.pyc,, +transformers/models/xlstm/__pycache__/configuration_xlstm.cpython-310.pyc,, +transformers/models/xlstm/__pycache__/modeling_xlstm.cpython-310.pyc,, +transformers/models/xlstm/configuration_xlstm.py,sha256=NYucYOU_UXCflnRmXuA0YJ-FS3lrmnlc70PSEPc6V58,12794 +transformers/models/xlstm/modeling_xlstm.py,sha256=CS13JKPTSuY7bsb6MS0dO8KNfHiKcoABhamvLA9ygsI,64628 +transformers/models/xmod/__init__.py,sha256=WLxIbzC8oCEkMrerWHTy7GLopz0mqocSaacdcyb_BhQ,989 +transformers/models/xmod/__pycache__/__init__.cpython-310.pyc,, +transformers/models/xmod/__pycache__/configuration_xmod.cpython-310.pyc,, +transformers/models/xmod/__pycache__/modeling_xmod.cpython-310.pyc,, +transformers/models/xmod/configuration_xmod.py,sha256=WRgBTFZJAwZLZDRECN4ZOXgjMRS4x8-kqCkitkP1ju8,8013 +transformers/models/xmod/modeling_xmod.py,sha256=Gz2IzbHwfe0vJxsncTvfxBIHpx2jyzOiYFyXRfoav6U,60008 +transformers/models/yolos/__init__.py,sha256=UlbQDtMQJaGRcin-iz6NOEFWT8otanBndRuw4VrWUiQ,1124 +transformers/models/yolos/__pycache__/__init__.cpython-310.pyc,, +transformers/models/yolos/__pycache__/configuration_yolos.cpython-310.pyc,, +transformers/models/yolos/__pycache__/image_processing_yolos.cpython-310.pyc,, +transformers/models/yolos/__pycache__/image_processing_yolos_fast.cpython-310.pyc,, +transformers/models/yolos/__pycache__/modeling_yolos.cpython-310.pyc,, +transformers/models/yolos/__pycache__/modular_yolos.cpython-310.pyc,, +transformers/models/yolos/configuration_yolos.py,sha256=QdDYiCoDudP_FO8EWGsOiLjBCjj-uFW92Jo9FtIQHVE,6983 +transformers/models/yolos/image_processing_yolos.py,sha256=i5r7c4yLZNh7Trt1TuSM7mgo8Y49GkLpwq5nJHwQN1U,63407 +transformers/models/yolos/image_processing_yolos_fast.py,sha256=-gx9V4c_ied9l8ikhekrN9oc67w2AbLwscOeU7zdhjw,29683 +transformers/models/yolos/modeling_yolos.py,sha256=UofdusXxXJYRttM3anPlb2vPz0NdToUFlA9FQ7XAWR0,27349 +transformers/models/yolos/modular_yolos.py,sha256=-mvDuzCGaZTvcN6psyLpf_Xi-svZCXT65OZbXkWvLGU,5043 +transformers/models/yoso/__init__.py,sha256=sCXsXYZuOQLFkZMexRb8qY7EJCftR54G_eO7qIUvdss,989 +transformers/models/yoso/__pycache__/__init__.cpython-310.pyc,, +transformers/models/yoso/__pycache__/configuration_yoso.cpython-310.pyc,, +transformers/models/yoso/__pycache__/modeling_yoso.cpython-310.pyc,, +transformers/models/yoso/configuration_yoso.py,sha256=uHNIWaL3Yo_kgcfhngJSSNYdH0Tdz51HqFKHUp8V0h8,6625 +transformers/models/yoso/modeling_yoso.py,sha256=d5Im1O2z9RPLnwlEtYeLbuVjbDORuo_4oxvSeP0KlL8,46052 +transformers/models/youtu/__init__.py,sha256=NiHuSA5gdHBMrrsi5C8nCRGL5LRvKkEBf2hAzzT-csU,996 +transformers/models/youtu/__pycache__/__init__.cpython-310.pyc,, +transformers/models/youtu/__pycache__/configuration_youtu.cpython-310.pyc,, +transformers/models/youtu/__pycache__/modeling_youtu.cpython-310.pyc,, +transformers/models/youtu/__pycache__/modular_youtu.cpython-310.pyc,, +transformers/models/youtu/configuration_youtu.py,sha256=mK2qGDgfHvclDtmMDy7MD8ya1EhzMogcEkPkgnv7Ge8,10169 +transformers/models/youtu/modeling_youtu.py,sha256=_91O8Ah6df8kHrvfC6vGAs0DxKtofn_lxFYIjPB7b-g,27113 +transformers/models/youtu/modular_youtu.py,sha256=YtpqL6Z_iptQ6dMXGmV81rlmNiiE3joezNLl_W4oVGg,10769 +transformers/models/zamba/__init__.py,sha256=iqZnf8BQ49TLcB4mYwIfuJeF4aGvYhOBRiGI6_74ZFk,991 +transformers/models/zamba/__pycache__/__init__.cpython-310.pyc,, +transformers/models/zamba/__pycache__/configuration_zamba.cpython-310.pyc,, +transformers/models/zamba/__pycache__/modeling_zamba.cpython-310.pyc,, +transformers/models/zamba/configuration_zamba.py,sha256=vcVAmOLJqr-j1vabfIr7KPoL-YumqRUoLCBrO2eHrqI,11262 +transformers/models/zamba/modeling_zamba.py,sha256=jxmsq7cEpvs6yVPHL17ZtXGaiVfTvhGjVZT0CDoaxEM,57682 +transformers/models/zamba2/__init__.py,sha256=3FgH8KelorllnKF6ncpKGREwZXt6YwsQ7NPS8W6jcmQ,993 +transformers/models/zamba2/__pycache__/__init__.cpython-310.pyc,, +transformers/models/zamba2/__pycache__/configuration_zamba2.cpython-310.pyc,, +transformers/models/zamba2/__pycache__/modeling_zamba2.cpython-310.pyc,, +transformers/models/zamba2/__pycache__/modular_zamba2.cpython-310.pyc,, +transformers/models/zamba2/configuration_zamba2.py,sha256=XohSWyWfQbj_fe5qpxver-1vOwH7Mc-uymLOnhb2bGA,12786 +transformers/models/zamba2/modeling_zamba2.py,sha256=LGzcYkdWD2ggA-jfRR24kJvSc95FaLYFqrCGSNoREmA,80856 +transformers/models/zamba2/modular_zamba2.py,sha256=FPUEmkIna7iIQl2PTn0NgkjYpHQkmNNt0y7Nfzq__Xk,54413 +transformers/models/zoedepth/__init__.py,sha256=BUGUeWtpJJRRdQGT1dIOi-B5v89Ae8eTTxbEmVqiu0k,1092 +transformers/models/zoedepth/__pycache__/__init__.cpython-310.pyc,, +transformers/models/zoedepth/__pycache__/configuration_zoedepth.cpython-310.pyc,, +transformers/models/zoedepth/__pycache__/image_processing_zoedepth.cpython-310.pyc,, +transformers/models/zoedepth/__pycache__/image_processing_zoedepth_fast.cpython-310.pyc,, +transformers/models/zoedepth/__pycache__/modeling_zoedepth.cpython-310.pyc,, +transformers/models/zoedepth/configuration_zoedepth.py,sha256=K3rj4yb0b5vBmIZTt95ZXokhsswemB0QjzvpznRPmPw,11207 +transformers/models/zoedepth/image_processing_zoedepth.py,sha256=leMBNG4KVn2bJeR3O48ybU2herpJqmYC9BfowM7wVfs,28963 +transformers/models/zoedepth/image_processing_zoedepth_fast.py,sha256=VfK2bJ8hQjPb2NGXUstR68S_N0EdksHtVus8qzRo8iw,11983 +transformers/models/zoedepth/modeling_zoedepth.py,sha256=PUC3GcBbI_JX3SiCIPxa_cmd6yx0ESNBr7f49JG6s_4,54321 +transformers/monkey_patching.py,sha256=uEOoWsO_srjco546jvmcgixW9T03U4KCWjF5UnW0GIY,13972 +transformers/optimization.py,sha256=eENDHMtyZIxHqcjNJFMtLREeiFfkjtzrXG6BIqvZtRM,39891 +transformers/pipelines/__init__.py,sha256=Q-ZRy40LtLTynlDU0kRenYOw26G0DKOY7_JWvokPAxk,65250 +transformers/pipelines/__pycache__/__init__.cpython-310.pyc,, +transformers/pipelines/__pycache__/any_to_any.cpython-310.pyc,, +transformers/pipelines/__pycache__/audio_classification.cpython-310.pyc,, +transformers/pipelines/__pycache__/audio_utils.cpython-310.pyc,, +transformers/pipelines/__pycache__/automatic_speech_recognition.cpython-310.pyc,, +transformers/pipelines/__pycache__/base.cpython-310.pyc,, +transformers/pipelines/__pycache__/depth_estimation.cpython-310.pyc,, +transformers/pipelines/__pycache__/document_question_answering.cpython-310.pyc,, +transformers/pipelines/__pycache__/feature_extraction.cpython-310.pyc,, +transformers/pipelines/__pycache__/fill_mask.cpython-310.pyc,, +transformers/pipelines/__pycache__/image_classification.cpython-310.pyc,, +transformers/pipelines/__pycache__/image_feature_extraction.cpython-310.pyc,, +transformers/pipelines/__pycache__/image_segmentation.cpython-310.pyc,, +transformers/pipelines/__pycache__/image_text_to_text.cpython-310.pyc,, +transformers/pipelines/__pycache__/keypoint_matching.cpython-310.pyc,, +transformers/pipelines/__pycache__/mask_generation.cpython-310.pyc,, +transformers/pipelines/__pycache__/object_detection.cpython-310.pyc,, +transformers/pipelines/__pycache__/pt_utils.cpython-310.pyc,, +transformers/pipelines/__pycache__/table_question_answering.cpython-310.pyc,, +transformers/pipelines/__pycache__/text_classification.cpython-310.pyc,, +transformers/pipelines/__pycache__/text_generation.cpython-310.pyc,, +transformers/pipelines/__pycache__/text_to_audio.cpython-310.pyc,, +transformers/pipelines/__pycache__/token_classification.cpython-310.pyc,, +transformers/pipelines/__pycache__/video_classification.cpython-310.pyc,, +transformers/pipelines/__pycache__/zero_shot_audio_classification.cpython-310.pyc,, +transformers/pipelines/__pycache__/zero_shot_classification.cpython-310.pyc,, +transformers/pipelines/__pycache__/zero_shot_image_classification.cpython-310.pyc,, +transformers/pipelines/__pycache__/zero_shot_object_detection.cpython-310.pyc,, +transformers/pipelines/any_to_any.py,sha256=wIWQPxvOEeKbxWvLs41oaiZh5wuuH5UXSNWqOQdj1yE,24684 +transformers/pipelines/audio_classification.py,sha256=JZg1fxtxoHEyWkI9i5IZik_Wiunm1u9PQqucW6Ij0kM,11074 +transformers/pipelines/audio_utils.py,sha256=WsfwXqFVypl161NslcANX5KSb8yNWZaJ8iMJc74oIqg,12191 +transformers/pipelines/automatic_speech_recognition.py,sha256=_knXQBXpUE5aiDSYRVeZTB0JBKrBgXzKepCgHc2WA2o,33511 +transformers/pipelines/base.py,sha256=6v5WW--IVjRAtstESG1wd_BeKNKTswBVJQpYJYlK_GI,58213 +transformers/pipelines/depth_estimation.py,sha256=DskN8ZSr9fG63bxB2MLoL6baSLd5AnXd8edlHZgyi6U,6115 +transformers/pipelines/document_question_answering.py,sha256=k8FRWjHuVT0RJNOfBozEp9LSGXm3HoucHy5_jV-AONQ,29473 +transformers/pipelines/feature_extraction.py,sha256=bvhwET2PwuMMHTXyO-IZTzuy78eoYUm-wO9mNbVyqTU,3406 +transformers/pipelines/fill_mask.py,sha256=3Au1MFhfq2x7fCP_66yKI1rnkvNTQk8TdORtcaulsLc,11064 +transformers/pipelines/image_classification.py,sha256=94dhxM9yixOWl6caJooKU_LkbUE20IqUcqsplVKFlfg,9880 +transformers/pipelines/image_feature_extraction.py,sha256=KdDTJoXMg8tuGGXmGEsXlEN3G_-qNiJB2NoRznjY13w,4794 +transformers/pipelines/image_segmentation.py,sha256=AkJiNMpo5h7P6yAOIrKzhuJqkv6cxT_lZTRVFLd-L_M,9748 +transformers/pipelines/image_text_to_text.py,sha256=pd-iL8nZiOHpGOpievzT4oaGvv-zHgn0cXLcYMW1Bak,21352 +transformers/pipelines/keypoint_matching.py,sha256=yf6w0ru1iPRKhkE3Z11lVGzPfnf_-zUCpTIHliRoa6s,7056 +transformers/pipelines/mask_generation.py,sha256=lUPtS9Bvz-VMX3vtGiqqzPu0vXVIO-rDNoCSYpu0MI4,15328 +transformers/pipelines/object_detection.py,sha256=B6iAuT0x5XaZxcZExjyC8fYGykaKDuiaiMMlihQ1F9g,8346 +transformers/pipelines/pt_utils.py,sha256=DtNVgO1ud1n0bYMwJclMvnIJqtoNs9aedcXuCvJL_SM,12816 +transformers/pipelines/table_question_answering.py,sha256=ZAkeA2UISRSkCMph6JEMuPnaoDgyD_7hAixIxO1cD_I,17171 +transformers/pipelines/text_classification.py,sha256=C66ihBlJVY0H-H7YlqY88RdbHhTuBROh7HIOVl4FNPs,9975 +transformers/pipelines/text_generation.py,sha256=0xxg6f0yuIoNZS9eK0j-xheTfP3Tez7jIYPrhEKxyZM,25312 +transformers/pipelines/text_to_audio.py,sha256=k_bc306uoF1l9dTEGErHNwswPQL1A-CBqztaROEdtuc,13103 +transformers/pipelines/token_classification.py,sha256=XN9Ddck_SQMqCFPXqn9u1B-_1INa3FgHXRCWrQ2gNZQ,28638 +transformers/pipelines/video_classification.py,sha256=zYygC0MKsUUuCtp-OJD7pmqUiuC354Z_QIKyp54vV0E,7628 +transformers/pipelines/zero_shot_audio_classification.py,sha256=iAcpyeO3QLGkliwHe7mha7AlDy2NNGv6WtbI7-5QqIY,6687 +transformers/pipelines/zero_shot_classification.py,sha256=B-0_i7OVYbyBA2wo3izjL__AxiEXW0JoOPNtyxMaqAQ,11976 +transformers/pipelines/zero_shot_image_classification.py,sha256=Ph0sKorUOLy5CZbQHLVZ5YH096vPMXirILFsu9hACCE,7644 +transformers/pipelines/zero_shot_object_detection.py,sha256=g6X6znGVEZYDbXUB1EuaglZgzRQJ_bbCYpbcLwRqs_8,10393 +transformers/processing_utils.py,sha256=rky9MuZdoyFoC0R8RL-Kzk9lYsGFXx0ZxOH33wFrBSU,96445 +transformers/py.typed,sha256=47DEQpj8HBSa-_TImW-5JCeuQeRkm5NMpJWZG3hSuFU,0 +transformers/pytorch_utils.py,sha256=HRrgl9LJtKFlFr1YjylByRs-yfiuWt6Q4Y2_qp9YiJQ,10077 +transformers/quantizers/__init__.py,sha256=S_xTSTbkDOvjLgR3jgR4EAkP_sc3NE8e38T-lllAaNo,800 +transformers/quantizers/__pycache__/__init__.cpython-310.pyc,, +transformers/quantizers/__pycache__/auto.cpython-310.pyc,, +transformers/quantizers/__pycache__/base.cpython-310.pyc,, +transformers/quantizers/__pycache__/quantizer_aqlm.cpython-310.pyc,, +transformers/quantizers/__pycache__/quantizer_auto_round.cpython-310.pyc,, +transformers/quantizers/__pycache__/quantizer_awq.cpython-310.pyc,, +transformers/quantizers/__pycache__/quantizer_bitnet.cpython-310.pyc,, +transformers/quantizers/__pycache__/quantizer_bnb_4bit.cpython-310.pyc,, +transformers/quantizers/__pycache__/quantizer_bnb_8bit.cpython-310.pyc,, +transformers/quantizers/__pycache__/quantizer_compressed_tensors.cpython-310.pyc,, +transformers/quantizers/__pycache__/quantizer_eetq.cpython-310.pyc,, +transformers/quantizers/__pycache__/quantizer_fbgemm_fp8.cpython-310.pyc,, +transformers/quantizers/__pycache__/quantizer_finegrained_fp8.cpython-310.pyc,, +transformers/quantizers/__pycache__/quantizer_fouroversix.cpython-310.pyc,, +transformers/quantizers/__pycache__/quantizer_fp_quant.cpython-310.pyc,, +transformers/quantizers/__pycache__/quantizer_gptq.cpython-310.pyc,, +transformers/quantizers/__pycache__/quantizer_higgs.cpython-310.pyc,, +transformers/quantizers/__pycache__/quantizer_hqq.cpython-310.pyc,, +transformers/quantizers/__pycache__/quantizer_metal.cpython-310.pyc,, +transformers/quantizers/__pycache__/quantizer_mxfp4.cpython-310.pyc,, +transformers/quantizers/__pycache__/quantizer_quanto.cpython-310.pyc,, +transformers/quantizers/__pycache__/quantizer_quark.cpython-310.pyc,, +transformers/quantizers/__pycache__/quantizer_sinq.cpython-310.pyc,, +transformers/quantizers/__pycache__/quantizer_spqr.cpython-310.pyc,, +transformers/quantizers/__pycache__/quantizer_torchao.cpython-310.pyc,, +transformers/quantizers/__pycache__/quantizer_vptq.cpython-310.pyc,, +transformers/quantizers/__pycache__/quantizers_utils.cpython-310.pyc,, +transformers/quantizers/auto.py,sha256=1PNBo_tL2L28gHyVWL2Cp1C6TGO_Hm5Nrj5-u_zYBtE,14229 +transformers/quantizers/base.py,sha256=z8jC3Dr_80-3IpUYRob_lccgG4NzF_As3luWUapFMdg,12727 +transformers/quantizers/quantizer_aqlm.py,sha256=V5P2jlHwMAkfXBDmieUSu85-MJRIZXG9WrOY4Zd6jvE,2567 +transformers/quantizers/quantizer_auto_round.py,sha256=VbVkIrKju6WyP5UrhgEVMBap46MWURP_M2WeHqqfpV4,2686 +transformers/quantizers/quantizer_awq.py,sha256=UEx7Mz9VA73hPKoKmvMV3yFENnY0LiyqRxCXoHcwl0g,3680 +transformers/quantizers/quantizer_bitnet.py,sha256=yblRZyo7cD2wGqA6wRYNVfz6i3kf3VEnUS9Fli3QvYI,4426 +transformers/quantizers/quantizer_bnb_4bit.py,sha256=4ru6Iza4jLd5xJ7I2snpTj6v1U7IbxffGg1i5kxPGuI,7087 +transformers/quantizers/quantizer_bnb_8bit.py,sha256=meDXj5J_aI3XkvRO5IHJlZhcmXu_J6lxqpIxzh1qFXE,6751 +transformers/quantizers/quantizer_compressed_tensors.py,sha256=TiDPs8OnwxYE1S6ZtkjGAyHkwCIqx1QRFQVOlRTNcsw,4781 +transformers/quantizers/quantizer_eetq.py,sha256=x6SJMlML06w9_slKyq2vQt43Y5To_j8bjTTPDkftRP4,3841 +transformers/quantizers/quantizer_fbgemm_fp8.py,sha256=qblr4bf775KbYhPuMPNQNvAGzZgOWryh4fScqOYjUsY,9722 +transformers/quantizers/quantizer_finegrained_fp8.py,sha256=-EaG0G_7AVCvQKfRwiMju1V0WdkPFzZpsw7L2qr3le0,6829 +transformers/quantizers/quantizer_fouroversix.py,sha256=e3GLc5cNZHWjaXS9dLada6eqeRdb0bP5I1r0LBKnz_U,3231 +transformers/quantizers/quantizer_fp_quant.py,sha256=zlGvtTAOd2YuIZIjQPSRLkLD7B9tdZCr2dCxf2OsazY,6197 +transformers/quantizers/quantizer_gptq.py,sha256=wrz1-E8jOCKJTW3BuhhAyYwTm5twc9j0E1KH4yl1wv4,4334 +transformers/quantizers/quantizer_higgs.py,sha256=1paXt3YWa1TuILsMbYvMpWzK9pivvxcwfRt5uD0xGuU,7390 +transformers/quantizers/quantizer_hqq.py,sha256=5Thh7fTBkY3wHYJiesN2Tcb3jNZuWeyAyCLtHuSBtfU,11059 +transformers/quantizers/quantizer_metal.py,sha256=hypnRDwtP54w_4VulDjGq2-IfN4skUxN8iykVWFZ9t0,4899 +transformers/quantizers/quantizer_mxfp4.py,sha256=pPnD8UUHnTiptS9ct0VRbvcHUmyCNyWWaDQAsE7F2f4,12620 +transformers/quantizers/quantizer_quanto.py,sha256=H0X93tCjDQCnqMsvAV9s1cCfk28htKH8jQ9szy2x4Kc,4761 +transformers/quantizers/quantizer_quark.py,sha256=-zkhx5YpOmU_-xcsOKJ1FzfgGLHMOMds0ULD57EU6Gg,4519 +transformers/quantizers/quantizer_sinq.py,sha256=_YavZy6XnqrOnGGUl2BK1cLYyraKKmCEDhb4RZD0TqQ,9482 +transformers/quantizers/quantizer_spqr.py,sha256=dPTgHzyvXjLTQ1U3YhjuUlOpagZ72nAxcrIfByrSgqA,2688 +transformers/quantizers/quantizer_torchao.py,sha256=tDbjLTt0W405fiGWNWnvt5g7rsFlLvWRs4cTXl2Ak_I,11498 +transformers/quantizers/quantizer_vptq.py,sha256=xmV5b_f0iJTbxkxJL9d1QPAcKls1HG6cPH1o3GqyA1o,2416 +transformers/quantizers/quantizers_utils.py,sha256=GqiyI9-Qf1hvdPwgsAzILMsElbQYsxAQBrYIm7gmagg,1717 +transformers/safetensors_conversion.py,sha256=aBJ_lN7RSXZ5uBQOu1BQY4eqlNkZCGhxIcVHhcsGSoU,4541 +transformers/testing_utils.py,sha256=gbDUH69RfxDbpJ9AmGOWiLCX_XziDzq5oGc2uBd9L10,157362 +transformers/time_series_utils.py,sha256=6wfH0kcAucf05T7HJcAAjETE2wcoNneAus2UDQRg_d4,7480 +transformers/tokenization_mistral_common.py,sha256=LzewHWd9K6ALXQopqAQ3bcqCAi6ytURuQjpSt3kqpCc,78584 +transformers/tokenization_python.py,sha256=ehIBCu9QazGFkCntd52HeZHLJvVy2GIfys-fHzKbu4Y,62393 +transformers/tokenization_utils_base.py,sha256=An1LZUhqOUiRY2ZS63Ai8LD5v3Blk4p-vOqDo_BWJt8,174559 +transformers/tokenization_utils_sentencepiece.py,sha256=eVBFeKcNFpODXnAtvHiLQvDk4POE-8BtAimXtAdHF_4,13649 +transformers/tokenization_utils_tokenizers.py,sha256=POR9yw96nXACh40mf4aOfBazlYAEJbzRy3mZq60XdDc,63138 +transformers/trainer.py,sha256=Bg7ab81YfnnK7KfD8kbqe6sa9BBHnJd2WERwuPSsSKg,215309 +transformers/trainer_callback.py,sha256=jCK-rwe3f4qecdrKk952h1DEaN8_Lp9NXS0ygtPXys8,33632 +transformers/trainer_jit_checkpoint.py,sha256=0UPaTOmfMyssbS_VPrtB-FIoNOf6jMk8BVymIGQDMaw,5274 +transformers/trainer_optimizer.py,sha256=nuoTHZBg4_5nXnScwDfhcj6lus_g2NFeP1G7KOrBY94,23966 +transformers/trainer_pt_utils.py,sha256=7LzAPaoMCCieajZ6cIl_51nuelHhK0AhSsDGf8ywd0E,57264 +transformers/trainer_seq2seq.py,sha256=jPTudxaPi771CEL6hWfjkGrrtChBnpdmlUnQNAe9CU8,18138 +transformers/trainer_utils.py,sha256=coz9oXMwsJ-9syNYFZ4dAMQ8u74yom7CokaPQBaBtVU,49764 +transformers/training_args.py,sha256=0jLOfq5rqF3z-9NP-YG5Nd7_IbeWlUI0qthnD0a98_0,138948 +transformers/training_args_seq2seq.py,sha256=Cx0RKqvzMAe0KNApHdI2n7jJvwX09I2NsHYP1MdqcRs,4308 +transformers/utils/__init__.py,sha256=XFhbnSia_SFBqXf9kcfsL2xY96bVemDqxDb6IWz-ctE,9353 +transformers/utils/__pycache__/__init__.cpython-310.pyc,, +transformers/utils/__pycache__/_typing.cpython-310.pyc,, +transformers/utils/__pycache__/attention_visualizer.cpython-310.pyc,, +transformers/utils/__pycache__/auto_docstring.cpython-310.pyc,, +transformers/utils/__pycache__/backbone_utils.cpython-310.pyc,, +transformers/utils/__pycache__/chat_parsing_utils.cpython-310.pyc,, +transformers/utils/__pycache__/chat_template_utils.cpython-310.pyc,, +transformers/utils/__pycache__/constants.cpython-310.pyc,, +transformers/utils/__pycache__/deprecation.cpython-310.pyc,, +transformers/utils/__pycache__/doc.cpython-310.pyc,, +transformers/utils/__pycache__/dummy_detectron2_objects.cpython-310.pyc,, +transformers/utils/__pycache__/dummy_essentia_and_librosa_and_pretty_midi_and_scipy_and_torch_objects.cpython-310.pyc,, +transformers/utils/__pycache__/dummy_mistral_common_objects.cpython-310.pyc,, +transformers/utils/__pycache__/dummy_music_objects.cpython-310.pyc,, +transformers/utils/__pycache__/dummy_pt_objects.cpython-310.pyc,, +transformers/utils/__pycache__/dummy_sentencepiece_and_tokenizers_objects.cpython-310.pyc,, +transformers/utils/__pycache__/dummy_speech_objects.cpython-310.pyc,, +transformers/utils/__pycache__/dummy_timm_and_torchvision_objects.cpython-310.pyc,, +transformers/utils/__pycache__/dummy_tokenizers_objects.cpython-310.pyc,, +transformers/utils/__pycache__/dummy_torchaudio_objects.cpython-310.pyc,, +transformers/utils/__pycache__/dummy_torchvision_objects.cpython-310.pyc,, +transformers/utils/__pycache__/dummy_vision_objects.cpython-310.pyc,, +transformers/utils/__pycache__/generic.cpython-310.pyc,, +transformers/utils/__pycache__/hp_naming.cpython-310.pyc,, +transformers/utils/__pycache__/hub.cpython-310.pyc,, +transformers/utils/__pycache__/import_utils.cpython-310.pyc,, +transformers/utils/__pycache__/kernel_config.cpython-310.pyc,, +transformers/utils/__pycache__/loading_report.cpython-310.pyc,, +transformers/utils/__pycache__/logging.cpython-310.pyc,, +transformers/utils/__pycache__/metrics.cpython-310.pyc,, +transformers/utils/__pycache__/notebook.cpython-310.pyc,, +transformers/utils/__pycache__/output_capturing.cpython-310.pyc,, +transformers/utils/__pycache__/peft_utils.cpython-310.pyc,, +transformers/utils/__pycache__/pytest_helpers.cpython-310.pyc,, +transformers/utils/__pycache__/quantization_config.cpython-310.pyc,, +transformers/utils/__pycache__/sentencepiece_model_pb2.cpython-310.pyc,, +transformers/utils/__pycache__/sentencepiece_model_pb2_new.cpython-310.pyc,, +transformers/utils/__pycache__/type_validators.cpython-310.pyc,, +transformers/utils/__pycache__/versions.cpython-310.pyc,, +transformers/utils/_typing.py,sha256=pGP1qiujhs76hDn23OFlIiufGfSDyjTZfknyHwHrUBA,4797 +transformers/utils/attention_visualizer.py,sha256=KOkA4PfH59GtcLR5RhcxBpJG6MR38jRnbP50aTd-9GY,10143 +transformers/utils/auto_docstring.py,sha256=t7liCf2FsBrbOY1MtNFFXL_6NFbnuY1-ZfVUBG1rReY,127642 +transformers/utils/backbone_utils.py,sha256=NBW7XA-8AA280RQ9sZaR6wYqy69bHeq0s_zpYlLN6us,699 +transformers/utils/chat_parsing_utils.py,sha256=7oo5EbIkP6tuWwsbKJ4ghZQbNXtTKqGJKCzmkK5T7OA,11277 +transformers/utils/chat_template_utils.py,sha256=vSW3qC_GWxMMSWLspjQQHMD3PZe3r27HkWzeKVRIXZU,24660 +transformers/utils/constants.py,sha256=sZsUwOnA3CbtN1svs9YoaNLTTsAc9RVaITsgpf8K4iI,282 +transformers/utils/deprecation.py,sha256=9eOb1v_hJIypO3SHeyOTCBAnJytxhrvGh8mXn6N6tL8,8031 +transformers/utils/doc.py,sha256=GDFiD2tFxHDC_5nj8U-xv9ZAgJ2wHv0ZNRiwKa05glk,36848 +transformers/utils/dummy_detectron2_objects.py,sha256=n7Pt_7sbVBNfohKGcOARB-ZcPcJRbjEAcoLd2vTXndU,340 +transformers/utils/dummy_essentia_and_librosa_and_pretty_midi_and_scipy_and_torch_objects.py,sha256=n6pY4s7zCII3dzo7Ejd0RviHa_pMateuDEwbbHgsTUY,902 +transformers/utils/dummy_mistral_common_objects.py,sha256=_NEeG5StQyLHKZ_4OyTgvyxkxMBawME8knKX1y8Bqr8,309 +transformers/utils/dummy_music_objects.py,sha256=1lxIebYUOdHJWMQ_T5IQgPgcO_wp_8YM_HGc3skuGVg,458 +transformers/utils/dummy_pt_objects.py,sha256=3KwElc_huy-ynj6RSKBZMT_5dWlfA8LVC2kKclNAxJo,12894 +transformers/utils/dummy_sentencepiece_and_tokenizers_objects.py,sha256=BgPLr8Wz8A-17K86x04N21CKXtWNQLJEWx2c4aZRqaA,286 +transformers/utils/dummy_speech_objects.py,sha256=9eFm1cjdsYOPBoAz9JTgP35Bg8WF2C9AZ_y1hFpKZdQ,465 +transformers/utils/dummy_timm_and_torchvision_objects.py,sha256=EFuC5z6IsKOqqowoUGviJ3KgTjzvdTTN7gGQ3it-4t0,324 +transformers/utils/dummy_tokenizers_objects.py,sha256=PFIh5nBDmhWG2XDGuwIyBGldm6b_jdZdL3E8t5A8FsY,304 +transformers/utils/dummy_torchaudio_objects.py,sha256=EG0q0JkedoNb_4ntsf6EyTOE6Nr1whvHOzHPKy1t7x0,847 +transformers/utils/dummy_torchvision_objects.py,sha256=BaUQGsNL0Xfj-HP-pOVXSKYw5UFaNlWD_Iso9D8muGw,479 +transformers/utils/dummy_vision_objects.py,sha256=GDbX7-GrqykExLY91SMhSf508DinS5NSFfavbeDsCMU,630 +transformers/utils/generic.py,sha256=0dLWJJiuTQ3N7u5uBXFuXOhLYIBbgNytl0m3LfUNOp4,34124 +transformers/utils/hp_naming.py,sha256=vqcOXcDOyqbISWo8-ClUJUOBVbZM1h08EcymTwcRthc,4979 +transformers/utils/hub.py,sha256=gjYQyes0iguCIqhuRlRwy4BAyfz5s1SmG0rDQ4VJub0,39193 +transformers/utils/import_utils.py,sha256=NButUBSB_t00nNmwY8EBMeyN8I-VZOP5WU4EuQzMejE,106457 +transformers/utils/kernel_config.py,sha256=kZIOPrEDxukoOlEmc1NAARfU2WPVjx5tVPJn1PhhZIo,10323 +transformers/utils/loading_report.py,sha256=51ySp8TyHWe976UG7is0dxg-vAl1ROrJjwkPtk_eN5E,10076 +transformers/utils/logging.py,sha256=wtofgcrI9_iWameFMeVNonwt1ObcQHreyf8WYykXcaw,12347 +transformers/utils/metrics.py,sha256=LEJk-c65bszQ78uWZqQtCVNJxcJZjZ2wgoYQ36Yk85A,15583 +transformers/utils/notebook.py,sha256=Wm3Z7k9wC1S-sGHoNs7rToIQ_yAHIBQ_Pwqw9TOhT0c,16031 +transformers/utils/output_capturing.py,sha256=9-bRbtB_Sz6bVZ2DvNVHUqziPpeHkbtcJdKPzTuQdT4,12630 +transformers/utils/peft_utils.py,sha256=lgB-0xIz8j1__nDS_ZIk5Uv00x4FTgC3_43RZmg0Giw,4841 +transformers/utils/pytest_helpers.py,sha256=WjWr38_XlTI7DkTdMAkKGo1pcSOYaq0uVwpD-PSV2IU,3571 +transformers/utils/quantization_config.py,sha256=FKdHjekOIWONZZSQ8Vouk9zv6sjmje1ZzcqBFHCI63Y,94132 +transformers/utils/sentencepiece_model_pb2.py,sha256=WcMZRm2-571XwxSfo-6FZih9fDy_Zl5mMwqrDrC1Dlg,50663 +transformers/utils/sentencepiece_model_pb2_new.py,sha256=ahaV--amhGIL3nXFCTHqezqxuGXm8SHr_C3Zvj7KbAY,6598 +transformers/utils/type_validators.py,sha256=QO7BI67wplR8tsQzgQBRb_P86JM4O4FjPHgDqbsSqe8,5559 +transformers/utils/versions.py,sha256=WCo4WQGtDdOJlRXZ8UJCA41sRBSySmmbSj6cZQGHbIg,4306 +transformers/video_processing_utils.py,sha256=-Kqxqthjhjrc5D1f5-jU2SXliNaIa-cLslwrS87H0WU,40925 +transformers/video_utils.py,sha256=7wMoBWSJBcBHdl65sZWt_X4eKp3nR1iC3uv79PLPf_Q,34395 diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers-5.3.0.dist-info/REQUESTED b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers-5.3.0.dist-info/REQUESTED new file mode 100644 index 0000000000000000000000000000000000000000..e69de29bb2d1d6434b8b29ae775ad8c2e48c5391 diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers-5.3.0.dist-info/WHEEL b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers-5.3.0.dist-info/WHEEL new file mode 100644 index 0000000000000000000000000000000000000000..1ef5583317a5e59140e3f1c85c2db91aec0961e8 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers-5.3.0.dist-info/WHEEL @@ -0,0 +1,5 @@ +Wheel-Version: 1.0 +Generator: setuptools (82.0.0) +Root-Is-Purelib: true +Tag: py3-none-any + diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers-5.3.0.dist-info/entry_points.txt b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers-5.3.0.dist-info/entry_points.txt new file mode 100644 index 0000000000000000000000000000000000000000..bf2a3b68e9616562bcdd157626656933ea607c29 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers-5.3.0.dist-info/entry_points.txt @@ -0,0 +1,2 @@ +[console_scripts] +transformers = transformers.cli.transformers:main diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers-5.3.0.dist-info/licenses/LICENSE b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers-5.3.0.dist-info/licenses/LICENSE new file mode 100644 index 0000000000000000000000000000000000000000..68b7d66c97d66c58de883ed0c451af2b3183e6f3 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers-5.3.0.dist-info/licenses/LICENSE @@ -0,0 +1,203 @@ +Copyright 2018- The Hugging Face team. All rights reserved. + + Apache License + Version 2.0, January 2004 + http://www.apache.org/licenses/ + + TERMS AND CONDITIONS FOR USE, REPRODUCTION, AND DISTRIBUTION + + 1. Definitions. + + "License" shall mean the terms and conditions for use, reproduction, + and distribution as defined by Sections 1 through 9 of this document. + + "Licensor" shall mean the copyright owner or entity authorized by + the copyright owner that is granting the License. + + "Legal Entity" shall mean the union of the acting entity and all + other entities that control, are controlled by, or are under common + control with that entity. For the purposes of this definition, + "control" means (i) the power, direct or indirect, to cause the + direction or management of such entity, whether by contract or + otherwise, or (ii) ownership of fifty percent (50%) or more of the + outstanding shares, or (iii) beneficial ownership of such entity. + + "You" (or "Your") shall mean an individual or Legal Entity + exercising permissions granted by this License. + + "Source" form shall mean the preferred form for making modifications, + including but not limited to software source code, documentation + source, and configuration files. + + "Object" form shall mean any form resulting from mechanical + transformation or translation of a Source form, including but + not limited to compiled object code, generated documentation, + and conversions to other media types. + + "Work" shall mean the work of authorship, whether in Source or + Object form, made available under the License, as indicated by a + copyright notice that is included in or attached to the work + (an example is provided in the Appendix below). + + "Derivative Works" shall mean any work, whether in Source or Object + form, that is based on (or derived from) the Work and for which the + editorial revisions, annotations, elaborations, or other modifications + represent, as a whole, an original work of authorship. For the purposes + of this License, Derivative Works shall not include works that remain + separable from, or merely link (or bind by name) to the interfaces of, + the Work and Derivative Works thereof. + + "Contribution" shall mean any work of authorship, including + the original version of the Work and any modifications or additions + to that Work or Derivative Works thereof, that is intentionally + submitted to Licensor for inclusion in the Work by the copyright owner + or by an individual or Legal Entity authorized to submit on behalf of + the copyright owner. For the purposes of this definition, "submitted" + means any form of electronic, verbal, or written communication sent + to the Licensor or its representatives, including but not limited to + communication on electronic mailing lists, source code control systems, + and issue tracking systems that are managed by, or on behalf of, the + Licensor for the purpose of discussing and improving the Work, but + excluding communication that is conspicuously marked or otherwise + designated in writing by the copyright owner as "Not a Contribution." + + "Contributor" shall mean Licensor and any individual or Legal Entity + on behalf of whom a Contribution has been received by Licensor and + subsequently incorporated within the Work. + + 2. Grant of Copyright License. Subject to the terms and conditions of + this License, each Contributor hereby grants to You a perpetual, + worldwide, non-exclusive, no-charge, royalty-free, irrevocable + copyright license to reproduce, prepare Derivative Works of, + publicly display, publicly perform, sublicense, and distribute the + Work and such Derivative Works in Source or Object form. + + 3. Grant of Patent License. Subject to the terms and conditions of + this License, each Contributor hereby grants to You a perpetual, + worldwide, non-exclusive, no-charge, royalty-free, irrevocable + (except as stated in this section) patent license to make, have made, + use, offer to sell, sell, import, and otherwise transfer the Work, + where such license applies only to those patent claims licensable + by such Contributor that are necessarily infringed by their + Contribution(s) alone or by combination of their Contribution(s) + with the Work to which such Contribution(s) was submitted. If You + institute patent litigation against any entity (including a + cross-claim or counterclaim in a lawsuit) alleging that the Work + or a Contribution incorporated within the Work constitutes direct + or contributory patent infringement, then any patent licenses + granted to You under this License for that Work shall terminate + as of the date such litigation is filed. + + 4. Redistribution. You may reproduce and distribute copies of the + Work or Derivative Works thereof in any medium, with or without + modifications, and in Source or Object form, provided that You + meet the following conditions: + + (a) You must give any other recipients of the Work or + Derivative Works a copy of this License; and + + (b) You must cause any modified files to carry prominent notices + stating that You changed the files; and + + (c) You must retain, in the Source form of any Derivative Works + that You distribute, all copyright, patent, trademark, and + attribution notices from the Source form of the Work, + excluding those notices that do not pertain to any part of + the Derivative Works; and + + (d) If the Work includes a "NOTICE" text file as part of its + distribution, then any Derivative Works that You distribute must + include a readable copy of the attribution notices contained + within such NOTICE file, excluding those notices that do not + pertain to any part of the Derivative Works, in at least one + of the following places: within a NOTICE text file distributed + as part of the Derivative Works; within the Source form or + documentation, if provided along with the Derivative Works; or, + within a display generated by the Derivative Works, if and + wherever such third-party notices normally appear. The contents + of the NOTICE file are for informational purposes only and + do not modify the License. You may add Your own attribution + notices within Derivative Works that You distribute, alongside + or as an addendum to the NOTICE text from the Work, provided + that such additional attribution notices cannot be construed + as modifying the License. + + You may add Your own copyright statement to Your modifications and + may provide additional or different license terms and conditions + for use, reproduction, or distribution of Your modifications, or + for any such Derivative Works as a whole, provided Your use, + reproduction, and distribution of the Work otherwise complies with + the conditions stated in this License. + + 5. Submission of Contributions. Unless You explicitly state otherwise, + any Contribution intentionally submitted for inclusion in the Work + by You to the Licensor shall be under the terms and conditions of + this License, without any additional terms or conditions. + Notwithstanding the above, nothing herein shall supersede or modify + the terms of any separate license agreement you may have executed + with Licensor regarding such Contributions. + + 6. Trademarks. This License does not grant permission to use the trade + names, trademarks, service marks, or product names of the Licensor, + except as required for reasonable and customary use in describing the + origin of the Work and reproducing the content of the NOTICE file. + + 7. Disclaimer of Warranty. Unless required by applicable law or + agreed to in writing, Licensor provides the Work (and each + Contributor provides its Contributions) on an "AS IS" BASIS, + WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or + implied, including, without limitation, any warranties or conditions + of TITLE, NON-INFRINGEMENT, MERCHANTABILITY, or FITNESS FOR A + PARTICULAR PURPOSE. You are solely responsible for determining the + appropriateness of using or redistributing the Work and assume any + risks associated with Your exercise of permissions under this License. + + 8. Limitation of Liability. In no event and under no legal theory, + whether in tort (including negligence), contract, or otherwise, + unless required by applicable law (such as deliberate and grossly + negligent acts) or agreed to in writing, shall any Contributor be + liable to You for damages, including any direct, indirect, special, + incidental, or consequential damages of any character arising as a + result of this License or out of the use or inability to use the + Work (including but not limited to damages for loss of goodwill, + work stoppage, computer failure or malfunction, or any and all + other commercial damages or losses), even if such Contributor + has been advised of the possibility of such damages. + + 9. Accepting Warranty or Additional Liability. While redistributing + the Work or Derivative Works thereof, You may choose to offer, + and charge a fee for, acceptance of support, warranty, indemnity, + or other liability obligations and/or rights consistent with this + License. However, in accepting such obligations, You may act only + on Your own behalf and on Your sole responsibility, not on behalf + of any other Contributor, and only if You agree to indemnify, + defend, and hold each Contributor harmless for any liability + incurred by, or claims asserted against, such Contributor by reason + of your accepting any such warranty or additional liability. + + END OF TERMS AND CONDITIONS + + APPENDIX: How to apply the Apache License to your work. + + To apply the Apache License to your work, attach the following + boilerplate notice, with the fields enclosed by brackets "[]" + replaced with your own identifying information. (Don't include + the brackets!) The text should be enclosed in the appropriate + comment syntax for the file format. We also recommend that a + file or class name and description of purpose be included on the + same "printed page" as the copyright notice for easier + identification within third-party archives. + + Copyright [yyyy] [name of copyright owner] + + Licensed under the Apache License, Version 2.0 (the "License"); + you may not use this file except in compliance with the License. + You may obtain a copy of the License at + + http://www.apache.org/licenses/LICENSE-2.0 + + Unless required by applicable law or agreed to in writing, software + distributed under the License is distributed on an "AS IS" BASIS, + WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + See the License for the specific language governing permissions and + limitations under the License. diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers-5.3.0.dist-info/top_level.txt b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers-5.3.0.dist-info/top_level.txt new file mode 100644 index 0000000000000000000000000000000000000000..976a2b1f3998279c10c413279a095be86bf69167 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers-5.3.0.dist-info/top_level.txt @@ -0,0 +1 @@ +transformers diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/parakeet/modeling_parakeet.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/parakeet/modeling_parakeet.py new file mode 100644 index 0000000000000000000000000000000000000000..23be85a2f8278a37078e1eb1d4c8304be407f809 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/parakeet/modeling_parakeet.py @@ -0,0 +1,814 @@ +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# This file was automatically generated from src/transformers/models/parakeet/modular_parakeet.py. +# Do NOT edit this file manually as any edits will be overwritten by the generation of +# the file from the modular. If any change should be done, please apply the change to the +# modular_parakeet.py file directly. One of our CI enforces this. +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# Copyright 2025 The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import math +from collections.abc import Callable +from dataclasses import dataclass + +import torch +from torch import nn + +from ... import initialization as init +from ...activations import ACT2FN +from ...integrations import use_kernel_func_from_hub, use_kernelized_func +from ...modeling_layers import GradientCheckpointingLayer +from ...modeling_outputs import BaseModelOutput, CausalLMOutput +from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel +from ...processing_utils import Unpack +from ...utils import ModelOutput, TransformersKwargs, auto_docstring, can_return_tuple +from ...utils.generic import maybe_autocast, merge_with_config_defaults +from ...utils.output_capturing import capture_outputs +from .configuration_parakeet import ParakeetCTCConfig, ParakeetEncoderConfig + + +@dataclass +@auto_docstring( + custom_intro=""" + Extends [~modeling_outputs.BaseModelOutput] to include the output attention mask since sequence length is not preserved in the model's forward. + """ +) +class ParakeetEncoderModelOutput(BaseModelOutput): + attention_mask: torch.Tensor | None = None + + +class ParakeetEncoderRelPositionalEncoding(nn.Module): + """Relative positional encoding for Parakeet.""" + + inv_freq: torch.Tensor # fix linting for `register_buffer` + + def __init__(self, config: ParakeetEncoderConfig, device=None): + super().__init__() + self.max_position_embeddings = config.max_position_embeddings + base = 10000.0 + inv_freq = 1.0 / ( + base + ** ( + torch.arange(0, config.hidden_size, 2, dtype=torch.int64).to(device=device, dtype=torch.float) + / config.hidden_size + ) + ) + + self.register_buffer("inv_freq", inv_freq, persistent=False) + + @torch.no_grad() + def forward(self, hidden_states: torch.Tensor): + seq_length = hidden_states.shape[1] + if seq_length > self.max_position_embeddings: + raise ValueError( + f"Sequence Length: {seq_length} has to be less or equal than " + f"config.max_position_embeddings {self.max_position_embeddings}." + ) + + position_ids = torch.arange(seq_length - 1, -seq_length, -1, device=hidden_states.device) + inv_freq_expanded = ( + self.inv_freq[None, :, None].float().expand(hidden_states.shape[0], -1, 1).to(hidden_states.device) + ) + position_ids_expanded = position_ids[None, None, :].float() + + device_type = ( + hidden_states.device.type + if isinstance(hidden_states.device.type, str) and hidden_states.device.type != "mps" + else "cpu" + ) + with maybe_autocast(device_type=device_type, enabled=False): # Force float32 + freqs = (inv_freq_expanded.float() @ position_ids_expanded.float()).transpose(1, 2) + sin = freqs.sin() + cos = freqs.cos() + # interleave sin and cos + pos_embed = torch.stack([sin, cos], dim=-1) + pos_embed = pos_embed.reshape(*pos_embed.shape[:-2], -1) + + return pos_embed.to(dtype=hidden_states.dtype) + + +class ParakeetEncoderFeedForward(nn.Module): + def __init__(self, config: ParakeetEncoderConfig): + super().__init__() + self.linear1 = nn.Linear(config.hidden_size, config.intermediate_size, bias=config.attention_bias) + self.activation = ACT2FN[config.hidden_act] + self.linear2 = nn.Linear(config.intermediate_size, config.hidden_size, bias=config.attention_bias) + self.activation_dropout = config.activation_dropout + + def forward(self, hidden_states): + hidden_states = self.activation(self.linear1(hidden_states)) + hidden_states = nn.functional.dropout(hidden_states, p=self.activation_dropout, training=self.training) + hidden_states = self.linear2(hidden_states) + return hidden_states + + +class ParakeetEncoderConvolutionModule(nn.Module): + def __init__(self, config: ParakeetEncoderConfig, module_config=None): + """ + Args: + config (ParakeetEncoderConfig): Configuration for the model. + module_config (dict): Configuration for the module (e.g., encoder or decoder). + """ + super().__init__() + channels = config.hidden_size + # kernel_size should be an odd number for 'SAME' padding + if module_config is None: + # e.g. using `ParakeetEncoderEncoderConfig` in src/transformers/models/parakeet_encoder/configuration_parakeet_encoder.py + kernel_size = config.conv_kernel_size + self.activation = ACT2FN[getattr(config, "hidden_act", "silu")] + else: + kernel_size = module_config["kernel_size"] + self.activation = ACT2FN[module_config.get("activation", "silu")] + self.padding = (kernel_size - 1) // 2 + self.pointwise_conv1 = nn.Conv1d( + channels, 2 * channels, kernel_size=1, stride=1, padding=0, bias=config.convolution_bias + ) + self.depthwise_conv = nn.Conv1d( + channels, + channels, + kernel_size, + stride=1, + padding=self.padding, + groups=channels, + bias=config.convolution_bias, + ) + self.norm = nn.BatchNorm1d(channels) + self.pointwise_conv2 = nn.Conv1d( + channels, channels, kernel_size=1, stride=1, padding=0, bias=config.convolution_bias + ) + + def forward(self, hidden_states, attention_mask=None): + """ + Compute convolution module. + + Args: + hidden_states (`torch.Tensor` of shape `(batch, time, channels)`): Input tensor. + attention_mask (`torch.Tensor` of shape `(batch, 1, time, time)`): Attention mask. + + Returns: + `torch.Tensor`: Output tensor of shape `(batch, time, channels)`. + + """ + # exchange the temporal dimension and the feature dimension + hidden_states = hidden_states.transpose(1, 2) + + # GLU mechanism, (batch_size, 2*channel, dim) + hidden_states = self.pointwise_conv1(hidden_states) + # (batch_size, channel, dim) + hidden_states = nn.functional.glu(hidden_states, dim=1) + + # Apply padding mask before convolution + if attention_mask is not None: + if attention_mask.dtype == torch.bool: + all_masked_rows = torch.all(~attention_mask, dim=2) + else: + all_masked_rows = torch.all(~(attention_mask == 0.0), dim=2) + hidden_states = hidden_states.masked_fill(all_masked_rows, 0.0) + + # 1D Depthwise Conv + hidden_states = self.depthwise_conv(hidden_states) + hidden_states = self.norm(hidden_states) + hidden_states = self.activation(hidden_states) + hidden_states = self.pointwise_conv2(hidden_states) + + return hidden_states.transpose(1, 2) + + +def rotate_half(x): + """Rotates half the hidden dims of the input.""" + x1 = x[..., : x.shape[-1] // 2] + x2 = x[..., x.shape[-1] // 2 :] + return torch.cat((-x2, x1), dim=-1) + + +@use_kernel_func_from_hub("rotary_pos_emb") +def apply_rotary_pos_emb(q, k, cos, sin, unsqueeze_dim=1): + """Applies Rotary Position Embedding to the query and key tensors. + + Args: + q (`torch.Tensor`): The query tensor. + k (`torch.Tensor`): The key tensor. + cos (`torch.Tensor`): The cosine part of the rotary embedding. + sin (`torch.Tensor`): The sine part of the rotary embedding. + unsqueeze_dim (`int`, *optional*, defaults to 1): + The 'unsqueeze_dim' argument specifies the dimension along which to unsqueeze cos[position_ids] and + sin[position_ids] so that they can be properly broadcasted to the dimensions of q and k. For example, note + that cos[position_ids] and sin[position_ids] have the shape [batch_size, seq_len, head_dim]. Then, if q and + k have the shape [batch_size, heads, seq_len, head_dim], then setting unsqueeze_dim=1 makes + cos[position_ids] and sin[position_ids] broadcastable to the shapes of q and k. Similarly, if q and k have + the shape [batch_size, seq_len, heads, head_dim], then set unsqueeze_dim=2. + Returns: + `tuple(torch.Tensor)` comprising of the query and key tensors rotated using the Rotary Position Embedding. + """ + cos = cos.unsqueeze(unsqueeze_dim) + sin = sin.unsqueeze(unsqueeze_dim) + q_embed = (q * cos) + (rotate_half(q) * sin) + k_embed = (k * cos) + (rotate_half(k) * sin) + return q_embed, k_embed + + +def repeat_kv(hidden_states: torch.Tensor, n_rep: int) -> torch.Tensor: + """ + This is the equivalent of torch.repeat_interleave(x, dim=1, repeats=n_rep). The hidden states go from (batch, + num_key_value_heads, seqlen, head_dim) to (batch, num_attention_heads, seqlen, head_dim) + """ + batch, num_key_value_heads, slen, head_dim = hidden_states.shape + if n_rep == 1: + return hidden_states + hidden_states = hidden_states[:, :, None, :, :].expand(batch, num_key_value_heads, n_rep, slen, head_dim) + return hidden_states.reshape(batch, num_key_value_heads * n_rep, slen, head_dim) + + +def eager_attention_forward( + module: nn.Module, + query: torch.Tensor, + key: torch.Tensor, + value: torch.Tensor, + attention_mask: torch.Tensor | None, + scaling: float, + dropout: float = 0.0, + **kwargs: Unpack[TransformersKwargs], +): + key_states = repeat_kv(key, module.num_key_value_groups) + value_states = repeat_kv(value, module.num_key_value_groups) + + attn_weights = torch.matmul(query, key_states.transpose(2, 3)) * scaling + if attention_mask is not None: + attn_weights = attn_weights + attention_mask + + attn_weights = nn.functional.softmax(attn_weights, dim=-1, dtype=torch.float32).to(query.dtype) + attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training) + attn_output = torch.matmul(attn_weights, value_states) + attn_output = attn_output.transpose(1, 2).contiguous() + + return attn_output, attn_weights + + +@use_kernelized_func(apply_rotary_pos_emb) +class ParakeetEncoderAttention(nn.Module): + """Multi-head attention with relative positional encoding. See section 3.3 of https://huggingface.co/papers/1901.02860.""" + + def __init__(self, config: ParakeetEncoderConfig, layer_idx: int): + super().__init__() + self.config = config + self.layer_idx = layer_idx + self.head_dim = getattr(config, "head_dim", config.hidden_size // config.num_attention_heads) + self.num_key_value_groups = config.num_attention_heads // config.num_key_value_heads + self.scaling = self.head_dim**-0.5 + self.attention_dropout = config.attention_dropout + self.is_causal = False + + self.q_proj = nn.Linear( + config.hidden_size, config.num_attention_heads * self.head_dim, bias=config.attention_bias + ) + self.k_proj = nn.Linear( + config.hidden_size, config.num_key_value_heads * self.head_dim, bias=config.attention_bias + ) + self.v_proj = nn.Linear( + config.hidden_size, config.num_key_value_heads * self.head_dim, bias=config.attention_bias + ) + self.o_proj = nn.Linear( + config.num_attention_heads * self.head_dim, config.hidden_size, bias=config.attention_bias + ) + # W_{k,R} projection + self.relative_k_proj = nn.Linear(config.hidden_size, config.num_attention_heads * self.head_dim, bias=False) + # global content bias + self.bias_u = nn.Parameter(torch.zeros(config.num_attention_heads, self.head_dim)) + # global positional bias + self.bias_v = nn.Parameter(torch.zeros(config.num_attention_heads, self.head_dim)) + + def forward( + self, + hidden_states: torch.Tensor, + position_embeddings: torch.Tensor | None, + attention_mask: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor, torch.Tensor]: + input_shape = hidden_states.shape[:-1] + batch_size, seq_length = input_shape + hidden_shape = (batch_size, seq_length, -1, self.head_dim) + + query_states = self.q_proj(hidden_states).view(hidden_shape).transpose(1, 2) + key_states = self.k_proj(hidden_states).view(hidden_shape).transpose(1, 2) + value_states = self.v_proj(hidden_states).view(hidden_shape).transpose(1, 2) + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, eager_attention_forward + ) + + query_states_with_bias_u = query_states + self.bias_u.view( + 1, self.config.num_attention_heads, 1, self.head_dim + ) + query_states_with_bias_v = query_states + self.bias_v.view( + 1, self.config.num_attention_heads, 1, self.head_dim + ) + + relative_key_states = self.relative_k_proj(position_embeddings) + relative_key_states = relative_key_states.view(batch_size, -1, self.config.num_attention_heads, self.head_dim) + + # terms (b) and (d) + matrix_bd = query_states_with_bias_v @ relative_key_states.permute(0, 2, 3, 1) + matrix_bd = self._rel_shift(matrix_bd) + matrix_bd = matrix_bd[..., :seq_length] + matrix_bd = matrix_bd * self.scaling + + if attention_mask is not None: + # here the original codebase uses -10000.0 rather than float("-inf") and then manual masked fill with 0.0s + # see: https://github.com/NVIDIA-NeMo/NeMo/blob/8cfedd7203462cb251a914e700e5605444277561/nemo/collections/asr/parts/submodules/multi_head_attention.py#L320-L340 + # we rather went for a straight-forward approach with float("-inf") + matrix_bd = matrix_bd.masked_fill_(attention_mask.logical_not(), float("-inf")) + + # will compute matrix_ac - terms (a) and (c) - and add matrix_bd + attn_output, attn_weights = attention_interface( + self, + query=query_states_with_bias_u, + key=key_states, + value=value_states, + attention_mask=matrix_bd, + dropout=0.0 if not self.training else self.attention_dropout, + scaling=self.scaling, + **kwargs, + ) + + attn_output = attn_output.reshape(*input_shape, -1).contiguous() + attn_output = self.o_proj(attn_output) + return attn_output, attn_weights + + def _rel_shift(self, attention_scores): + """Relative position shift for Shaw et al. style attention. See appendix B of https://huggingface.co/papers/1901.02860.""" + batch_size, num_heads, query_length, position_length = attention_scores.shape + attention_scores = nn.functional.pad(attention_scores, pad=(1, 0)) + attention_scores = attention_scores.view(batch_size, num_heads, -1, query_length) + attention_scores = attention_scores[:, :, 1:].view(batch_size, num_heads, query_length, position_length) + return attention_scores + + +class ParakeetEncoderSubsamplingConv2D(nn.Module): + def __init__(self, config: ParakeetEncoderConfig): + super().__init__() + + self.kernel_size = config.subsampling_conv_kernel_size + self.stride = config.subsampling_conv_stride + self.channels = config.subsampling_conv_channels + self.padding = (self.kernel_size - 1) // 2 + self.num_layers = int(math.log2(config.subsampling_factor)) + + # define layers + self.layers = nn.ModuleList() + self.layers.append( + nn.Conv2d(1, self.channels, kernel_size=self.kernel_size, stride=self.stride, padding=self.padding) + ) + self.layers.append(nn.ReLU()) + for i in range(self.num_layers - 1): + # depthwise conv + self.layers.append( + nn.Conv2d( + self.channels, + self.channels, + kernel_size=self.kernel_size, + stride=self.stride, + padding=self.padding, + groups=self.channels, + ) + ) + # pointwise conv + self.layers.append(nn.Conv2d(self.channels, self.channels, kernel_size=1)) + # activation + self.layers.append(nn.ReLU()) + + out_length = config.num_mel_bins // (self.stride**self.num_layers) + self.linear = nn.Linear(config.subsampling_conv_channels * out_length, config.hidden_size, bias=True) + + def _get_output_length(self, input_lengths: torch.Tensor, conv_layer: nn.Conv2d): + if hasattr(conv_layer, "stride") and conv_layer.stride != (1, 1): + padding = conv_layer.padding + kernel_size = conv_layer.kernel_size[0] + stride = conv_layer.stride[0] + + output_lengths = (input_lengths + padding[0] + padding[1] - kernel_size) // stride + 1 + return output_lengths + + return input_lengths + + def forward(self, input_features: torch.Tensor, attention_mask: torch.Tensor = None): + hidden_states = input_features.unsqueeze(1) + current_lengths = attention_mask.sum(-1) if attention_mask is not None else None + + for layer in self.layers: + hidden_states = layer(hidden_states) + + # mask the hidden states + if isinstance(layer, nn.Conv2d) and attention_mask is not None: + current_lengths = self._get_output_length(current_lengths, layer) + current_seq_length = hidden_states.shape[2] + channel_mask = ( + torch.arange(current_seq_length, device=attention_mask.device) < current_lengths[:, None] + ) + hidden_states *= channel_mask[:, None, :, None] + + hidden_states = hidden_states.transpose(1, 2).reshape(hidden_states.shape[0], hidden_states.shape[2], -1) + hidden_states = self.linear(hidden_states) + + return hidden_states + + +class ParakeetEncoderBlock(GradientCheckpointingLayer): + def __init__(self, config: ParakeetEncoderConfig, layer_idx: int | None = None): + super().__init__() + self.gradient_checkpointing = False + + self.feed_forward1 = ParakeetEncoderFeedForward(config) + self.self_attn = ParakeetEncoderAttention(config, layer_idx) + self.conv = ParakeetEncoderConvolutionModule(config) + self.feed_forward2 = ParakeetEncoderFeedForward(config) + + self.norm_feed_forward1 = nn.LayerNorm(config.hidden_size) + self.norm_self_att = nn.LayerNorm(config.hidden_size) + self.norm_conv = nn.LayerNorm(config.hidden_size) + self.norm_feed_forward2 = nn.LayerNorm(config.hidden_size) + self.norm_out = nn.LayerNorm(config.hidden_size) + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.Tensor | None = None, + position_embeddings: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> torch.Tensor: + residual = hidden_states + hidden_states = self.feed_forward1(self.norm_feed_forward1(hidden_states)) + hidden_states = residual + 0.5 * hidden_states # the conformer architecture uses a factor of 0.5 + + normalized_hidden_states = self.norm_self_att(hidden_states) + attn_output, _ = self.self_attn( + hidden_states=normalized_hidden_states, + attention_mask=attention_mask, + position_embeddings=position_embeddings, + **kwargs, + ) + hidden_states = hidden_states + attn_output + + conv_output = self.conv(self.norm_conv(hidden_states), attention_mask=attention_mask) + hidden_states = hidden_states + conv_output + + ff2_output = self.feed_forward2(self.norm_feed_forward2(hidden_states)) + hidden_states = hidden_states + 0.5 * ff2_output # the conformer architecture uses a factor of 0.5 + + hidden_states = self.norm_out(hidden_states) + + return hidden_states + + +@auto_docstring +class ParakeetPreTrainedModel(PreTrainedModel): + config: ParakeetCTCConfig + base_model_prefix = "model" + main_input_name = "input_features" + input_modalities = "audio" + supports_gradient_checkpointing = True + _no_split_modules = ["ParakeetEncoderBlock"] + _supports_flat_attention_mask = True + _supports_sdpa = True + _supports_flex_attn = True + + # TODO: @eustlb, add support when flash attention supports custom attention bias + _supports_flash_attn = False + + _can_compile_fullgraph = True + _supports_attention_backend = True + _can_record_outputs = { + "hidden_states": ParakeetEncoderBlock, + "attentions": ParakeetEncoderAttention, + } + + @torch.no_grad() + def _init_weights(self, module): + super()._init_weights(module) + + if hasattr(self.config, "initializer_range"): + std = self.config.initializer_range + else: + # 0.02 is the standard default value across the library + std = getattr(self.config.get_text_config(), "initializer_range", 0.02) + + if isinstance(module, ParakeetEncoderAttention): + # Initialize positional bias parameters + init.normal_(module.bias_u, mean=0.0, std=std) + init.normal_(module.bias_v, mean=0.0, std=std) + elif isinstance(module, ParakeetEncoderRelPositionalEncoding): + inv_freq = 1.0 / ( + 10000.0 ** (torch.arange(0, self.config.hidden_size, 2, dtype=torch.int64) / self.config.hidden_size) + ) + init.copy_(module.inv_freq, inv_freq) + + def _get_subsampling_output_length(self, input_lengths: torch.Tensor): + encoder_config = self.config.encoder_config if isinstance(self.config, ParakeetCTCConfig) else self.config + + kernel_size = encoder_config.subsampling_conv_kernel_size + stride = encoder_config.subsampling_conv_stride + num_layers = int(math.log2(encoder_config.subsampling_factor)) + + all_paddings = (kernel_size - 1) // 2 * 2 + add_pad = all_paddings - kernel_size + lengths = input_lengths + + for _ in range(num_layers): + lengths = torch.div(lengths.to(dtype=torch.float) + add_pad, stride) + 1.0 + lengths = torch.floor(lengths) + + return lengths.to(dtype=torch.int) + + def _get_output_attention_mask(self, attention_mask: torch.Tensor, target_length: int | None = None): + """ + Convert the input attention mask to its subsampled form. `target_length` sets the desired output length, useful + when the attention mask length differs from `sum(-1).max()` (i.e., when the longest sequence in the batch is padded) + """ + output_lengths = self._get_subsampling_output_length(attention_mask.sum(-1)) + # Use target_length if provided, otherwise use max length in batch + max_length = target_length if target_length is not None else output_lengths.max() + attention_mask = torch.arange(max_length, device=attention_mask.device) < output_lengths[:, None] + return attention_mask + + +@auto_docstring( + custom_intro=""" + The Parakeet Encoder model, based on the [Fast Conformer architecture](https://huggingface.co/papers/2305.05084). + """ +) +class ParakeetEncoder(ParakeetPreTrainedModel): + config: ParakeetEncoderConfig + base_model_prefix = "encoder" + + def __init__(self, config: ParakeetEncoderConfig): + super().__init__(config) + self.config = config + self.gradient_checkpointing = False + + self.dropout = config.dropout + self.dropout_positions = config.dropout_positions + self.layerdrop = config.layerdrop + + self.input_scale = math.sqrt(config.hidden_size) if config.scale_input else 1.0 + self.subsampling = ParakeetEncoderSubsamplingConv2D(config) + self.encode_positions = ParakeetEncoderRelPositionalEncoding(config) + + self.layers = nn.ModuleList( + [ParakeetEncoderBlock(config, layer_idx) for layer_idx in range(config.num_hidden_layers)] + ) + + self.post_init() + + @auto_docstring + @merge_with_config_defaults + @capture_outputs + @can_return_tuple + def forward( + self, + input_features: torch.Tensor, + attention_mask: torch.Tensor | None = None, + output_attention_mask: bool | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> BaseModelOutput: + r""" + output_attention_mask (`bool`, *optional*): + Whether to return the output attention mask. + + Example: + + ```python + >>> from transformers import AutoProcessor, ParakeetEncoder + >>> from datasets import load_dataset, Audio + + >>> model_id = "nvidia/parakeet-ctc-1.1b" + >>> processor = AutoProcessor.from_pretrained(model_id) + >>> encoder = ParakeetEncoder.from_pretrained(model_id) + + >>> ds = load_dataset("hf-internal-testing/librispeech_asr_dummy", "clean", split="validation") + >>> ds = ds.cast_column("audio", Audio(sampling_rate=processor.feature_extractor.sampling_rate)) + + >>> inputs = processor(ds[0]["audio"]["array"]) + >>> encoder_outputs = encoder(**inputs) + + >>> print(encoder_outputs.last_hidden_state.shape) + ``` + """ + + hidden_states = self.subsampling(input_features, attention_mask) + hidden_states = hidden_states * self.input_scale + position_embeddings = self.encode_positions(hidden_states) + + hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training) + position_embeddings = nn.functional.dropout( + position_embeddings, p=self.dropout_positions, training=self.training + ) + + if attention_mask is not None: + output_mask = self._get_output_attention_mask(attention_mask, target_length=hidden_states.shape[1]) + attention_mask = output_mask.unsqueeze(1).expand(-1, hidden_states.shape[1], -1) + attention_mask = attention_mask & attention_mask.transpose(1, 2) + attention_mask = attention_mask.unsqueeze(1) + + for encoder_layer in self.layers: + # add LayerDrop (see https://huggingface.co/papers/1909.11556 for description) + to_drop = False + if self.training: + dropout_probability = torch.rand([]) + if dropout_probability < self.layerdrop: # skip the layer + to_drop = True + + if not to_drop: + hidden_states = encoder_layer( + hidden_states, + attention_mask=attention_mask, + position_embeddings=position_embeddings, + **kwargs, + ) + + return ParakeetEncoderModelOutput( + last_hidden_state=hidden_states, attention_mask=output_mask.int() if output_attention_mask else None + ) + + +@dataclass +class ParakeetGenerateOutput(ModelOutput): + """ + Outputs of Parakeet models. + + Args: + sequences (`torch.LongTensor` of shape `(batch_size, sequence_length)`): + The generated sequences. The second dimension (sequence_length) is either equal to `max_length` or shorter + if all batches finished early due to the `eos_token_id`. + logits (`tuple(torch.FloatTensor)` *optional*, returned when `output_logits=True`): + Unprocessed prediction scores of the language modeling head (scores for each vocabulary token before SoftMax) + at each generation step. Tuple of `torch.FloatTensor` with up to `max_new_tokens` elements (one element for + each generated token), with each tensor of shape `(batch_size, config.vocab_size)`. + attentions (`tuple(tuple(torch.FloatTensor))`, *optional*, returned when `output_attentions=True`): + Tuple (one element for each generated token) of tuples (one element for each layer of the decoder) of + `torch.FloatTensor` of shape `(batch_size, num_heads, generated_length, sequence_length)`. + hidden_states (`tuple(tuple(torch.FloatTensor))`, *optional*, returned when `output_hidden_states=True`): + Tuple (one element for each generated token) of tuples (one element for each layer of the decoder) of + `torch.FloatTensor` of shape `(batch_size, generated_length, hidden_size)`. + """ + + sequences: torch.LongTensor + logits: tuple[torch.FloatTensor] | None = None + attentions: tuple[tuple[torch.FloatTensor]] | None = None + hidden_states: tuple[tuple[torch.FloatTensor]] | None = None + + +@auto_docstring( + custom_intro=""" + Parakeet Encoder with a Connectionist Temporal Classification (CTC) head. + """ +) +class ParakeetForCTC(ParakeetPreTrainedModel): + config: ParakeetCTCConfig + + def __init__(self, config: ParakeetCTCConfig): + super().__init__(config) + self.encoder = ParakeetEncoder(config.encoder_config) + # Conv rather than linear to be consistent with NeMO decoding layer + self.ctc_head = nn.Conv1d(config.encoder_config.hidden_size, config.vocab_size, kernel_size=1) + + self.post_init() + + @auto_docstring + @can_return_tuple + def forward( + self, + input_features: torch.Tensor, + attention_mask: torch.Tensor | None = None, + labels: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> CausalLMOutput: + r""" + Example: + + ```python + >>> from transformers import AutoProcessor, ParakeetForCTC + >>> from datasets import load_dataset, Audio + + >>> model_id = "nvidia/parakeet-ctc-1.1b" + >>> processor = AutoProcessor.from_pretrained(model_id) + >>> model = ParakeetForCTC.from_pretrained(model_id) + + >>> ds = load_dataset("hf-internal-testing/librispeech_asr_dummy", "clean", split="validation") + >>> ds = ds.cast_column("audio", Audio(sampling_rate=processor.feature_extractor.sampling_rate)) + + >>> inputs = processor(ds[0]["audio"]["array"], text=ds[0]["text"]) + >>> outputs = model(**inputs) + + >>> print(outputs.loss) + ```""" + + encoder_outputs = self.encoder( + input_features=input_features, + attention_mask=attention_mask, + **kwargs, + ) + + hidden_states = encoder_outputs.last_hidden_state + logits = self.ctc_head(hidden_states.transpose(1, 2)).transpose(1, 2) + + loss = None + if labels is not None: + # retrieve loss input_lengths from attention_mask + attention_mask = ( + attention_mask if attention_mask is not None else torch.ones_like(input_features, dtype=torch.long) + ) + input_lengths = self._get_subsampling_output_length(attention_mask.sum(-1)) + + # assuming that padded tokens are filled with -100 + # when not being attended to + labels_mask = labels != self.config.pad_token_id + target_lengths = labels_mask.sum(-1) + flattened_targets = labels.masked_select(labels_mask) + + # ctc_loss doesn't support fp16 + log_probs = nn.functional.log_softmax(logits, dim=-1, dtype=torch.float32).transpose(0, 1) + + with torch.backends.cudnn.flags(enabled=False): + loss = nn.functional.ctc_loss( + log_probs, + flattened_targets, + input_lengths, + target_lengths, + blank=self.config.pad_token_id, + reduction=self.config.ctc_loss_reduction, + zero_infinity=self.config.ctc_zero_infinity, + ) + + return CausalLMOutput( + loss=loss, + logits=logits, + hidden_states=encoder_outputs.hidden_states, + attentions=encoder_outputs.attentions, + ) + + @torch.no_grad() + def generate( + self, + input_features: torch.Tensor, + attention_mask: torch.Tensor | None = None, + return_dict_in_generate: bool = False, + **kwargs: Unpack[TransformersKwargs], + ) -> ParakeetGenerateOutput | torch.LongTensor: + r""" + Example: + + ```python + >>> from transformers import AutoProcessor, ParakeetForCTC + >>> from datasets import load_dataset, Audio + + >>> model_id = "nvidia/parakeet-ctc-1.1b" + >>> processor = AutoProcessor.from_pretrained(model_id) + >>> model = ParakeetForCTC.from_pretrained(model_id) + + >>> ds = load_dataset("hf-internal-testing/librispeech_asr_dummy", "clean", split="validation") + >>> ds = ds.cast_column("audio", Audio(sampling_rate=processor.feature_extractor.sampling_rate)) + + >>> inputs = processor(ds[0]["audio"]["array"], text=ds[0]["text"]) + >>> predicted_ids = model.generate(**inputs) + >>> transcription = processor.batch_decode(predicted_ids, skip_special_tokens=True) + + >>> print(transcription) + ``` + """ + kwargs["return_dict"] = True + outputs: CausalLMOutput = self.forward( + input_features=input_features, + attention_mask=attention_mask, + **kwargs, + ) + + # greedy decoding + sequences = outputs.logits.argmax(dim=-1) + + # mask out padded tokens + if attention_mask is not None: + attention_mask = self._get_output_attention_mask(attention_mask, target_length=sequences.shape[1]) + sequences[~attention_mask] = self.config.pad_token_id + + if return_dict_in_generate: + return ParakeetGenerateOutput( + sequences=sequences, + logits=outputs.logits, + attentions=outputs.attentions, + hidden_states=outputs.hidden_states, + ) + + return sequences + + +__all__ = ["ParakeetForCTC", "ParakeetEncoder", "ParakeetPreTrainedModel"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/parakeet/modular_parakeet.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/parakeet/modular_parakeet.py new file mode 100644 index 0000000000000000000000000000000000000000..93ef18b1fa4917d956690e22df1c662d7f7719e7 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/parakeet/modular_parakeet.py @@ -0,0 +1,653 @@ +# Copyright 2025 The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""PyTorch Parakeet model.""" + +import math +from collections.abc import Callable +from dataclasses import dataclass + +import torch +from torch import nn + +from ... import initialization as init +from ...activations import ACT2FN +from ...modeling_layers import GradientCheckpointingLayer +from ...modeling_outputs import BaseModelOutput, CausalLMOutput +from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel +from ...processing_utils import Unpack +from ...utils import ModelOutput, TransformersKwargs, auto_docstring, can_return_tuple +from ...utils.generic import maybe_autocast, merge_with_config_defaults +from ...utils.output_capturing import capture_outputs +from ..fastspeech2_conformer.modeling_fastspeech2_conformer import FastSpeech2ConformerConvolutionModule +from ..llama.modeling_llama import LlamaAttention, eager_attention_forward +from .configuration_parakeet import ParakeetCTCConfig, ParakeetEncoderConfig + + +@dataclass +@auto_docstring( + custom_intro=""" + Extends [~modeling_outputs.BaseModelOutput] to include the output attention mask since sequence length is not preserved in the model's forward. + """ +) +class ParakeetEncoderModelOutput(BaseModelOutput): + attention_mask: torch.Tensor | None = None + + +class ParakeetEncoderRelPositionalEncoding(nn.Module): + """Relative positional encoding for Parakeet.""" + + inv_freq: torch.Tensor # fix linting for `register_buffer` + + def __init__(self, config: ParakeetEncoderConfig, device=None): + super().__init__() + self.max_position_embeddings = config.max_position_embeddings + base = 10000.0 + inv_freq = 1.0 / ( + base + ** ( + torch.arange(0, config.hidden_size, 2, dtype=torch.int64).to(device=device, dtype=torch.float) + / config.hidden_size + ) + ) + + self.register_buffer("inv_freq", inv_freq, persistent=False) + + @torch.no_grad() + def forward(self, hidden_states: torch.Tensor): + seq_length = hidden_states.shape[1] + if seq_length > self.max_position_embeddings: + raise ValueError( + f"Sequence Length: {seq_length} has to be less or equal than " + f"config.max_position_embeddings {self.max_position_embeddings}." + ) + + position_ids = torch.arange(seq_length - 1, -seq_length, -1, device=hidden_states.device) + inv_freq_expanded = ( + self.inv_freq[None, :, None].float().expand(hidden_states.shape[0], -1, 1).to(hidden_states.device) + ) + position_ids_expanded = position_ids[None, None, :].float() + + device_type = ( + hidden_states.device.type + if isinstance(hidden_states.device.type, str) and hidden_states.device.type != "mps" + else "cpu" + ) + with maybe_autocast(device_type=device_type, enabled=False): # Force float32 + freqs = (inv_freq_expanded.float() @ position_ids_expanded.float()).transpose(1, 2) + sin = freqs.sin() + cos = freqs.cos() + # interleave sin and cos + pos_embed = torch.stack([sin, cos], dim=-1) + pos_embed = pos_embed.reshape(*pos_embed.shape[:-2], -1) + + return pos_embed.to(dtype=hidden_states.dtype) + + +class ParakeetEncoderFeedForward(nn.Module): + def __init__(self, config: ParakeetEncoderConfig): + super().__init__() + self.linear1 = nn.Linear(config.hidden_size, config.intermediate_size, bias=config.attention_bias) + self.activation = ACT2FN[config.hidden_act] + self.linear2 = nn.Linear(config.intermediate_size, config.hidden_size, bias=config.attention_bias) + self.activation_dropout = config.activation_dropout + + def forward(self, hidden_states): + hidden_states = self.activation(self.linear1(hidden_states)) + hidden_states = nn.functional.dropout(hidden_states, p=self.activation_dropout, training=self.training) + hidden_states = self.linear2(hidden_states) + return hidden_states + + +class ParakeetEncoderConvolutionModule(FastSpeech2ConformerConvolutionModule): + def __init__(self, config: ParakeetEncoderConfig, module_config=None): + super().__init__(config, module_config) + + +class ParakeetEncoderAttention(LlamaAttention): + """Multi-head attention with relative positional encoding. See section 3.3 of https://huggingface.co/papers/1901.02860.""" + + def __init__(self, config: ParakeetEncoderConfig, layer_idx: int): + super().__init__(config, layer_idx=layer_idx) + self.is_causal = False + # W_{k,R} projection + self.relative_k_proj = nn.Linear(config.hidden_size, config.num_attention_heads * self.head_dim, bias=False) + # global content bias + self.bias_u = nn.Parameter(torch.zeros(config.num_attention_heads, self.head_dim)) + # global positional bias + self.bias_v = nn.Parameter(torch.zeros(config.num_attention_heads, self.head_dim)) + + def forward( + self, + hidden_states: torch.Tensor, + position_embeddings: torch.Tensor | None, + attention_mask: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor, torch.Tensor]: + input_shape = hidden_states.shape[:-1] + batch_size, seq_length = input_shape + hidden_shape = (batch_size, seq_length, -1, self.head_dim) + + query_states = self.q_proj(hidden_states).view(hidden_shape).transpose(1, 2) + key_states = self.k_proj(hidden_states).view(hidden_shape).transpose(1, 2) + value_states = self.v_proj(hidden_states).view(hidden_shape).transpose(1, 2) + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, eager_attention_forward + ) + + query_states_with_bias_u = query_states + self.bias_u.view( + 1, self.config.num_attention_heads, 1, self.head_dim + ) + query_states_with_bias_v = query_states + self.bias_v.view( + 1, self.config.num_attention_heads, 1, self.head_dim + ) + + relative_key_states = self.relative_k_proj(position_embeddings) + relative_key_states = relative_key_states.view(batch_size, -1, self.config.num_attention_heads, self.head_dim) + + # terms (b) and (d) + matrix_bd = query_states_with_bias_v @ relative_key_states.permute(0, 2, 3, 1) + matrix_bd = self._rel_shift(matrix_bd) + matrix_bd = matrix_bd[..., :seq_length] + matrix_bd = matrix_bd * self.scaling + + if attention_mask is not None: + # here the original codebase uses -10000.0 rather than float("-inf") and then manual masked fill with 0.0s + # see: https://github.com/NVIDIA-NeMo/NeMo/blob/8cfedd7203462cb251a914e700e5605444277561/nemo/collections/asr/parts/submodules/multi_head_attention.py#L320-L340 + # we rather went for a straight-forward approach with float("-inf") + matrix_bd = matrix_bd.masked_fill_(attention_mask.logical_not(), float("-inf")) + + # will compute matrix_ac - terms (a) and (c) - and add matrix_bd + attn_output, attn_weights = attention_interface( + self, + query=query_states_with_bias_u, + key=key_states, + value=value_states, + attention_mask=matrix_bd, + dropout=0.0 if not self.training else self.attention_dropout, + scaling=self.scaling, + **kwargs, + ) + + attn_output = attn_output.reshape(*input_shape, -1).contiguous() + attn_output = self.o_proj(attn_output) + return attn_output, attn_weights + + def _rel_shift(self, attention_scores): + """Relative position shift for Shaw et al. style attention. See appendix B of https://huggingface.co/papers/1901.02860.""" + batch_size, num_heads, query_length, position_length = attention_scores.shape + attention_scores = nn.functional.pad(attention_scores, pad=(1, 0)) + attention_scores = attention_scores.view(batch_size, num_heads, -1, query_length) + attention_scores = attention_scores[:, :, 1:].view(batch_size, num_heads, query_length, position_length) + return attention_scores + + +class ParakeetEncoderSubsamplingConv2D(nn.Module): + def __init__(self, config: ParakeetEncoderConfig): + super().__init__() + + self.kernel_size = config.subsampling_conv_kernel_size + self.stride = config.subsampling_conv_stride + self.channels = config.subsampling_conv_channels + self.padding = (self.kernel_size - 1) // 2 + self.num_layers = int(math.log2(config.subsampling_factor)) + + # define layers + self.layers = nn.ModuleList() + self.layers.append( + nn.Conv2d(1, self.channels, kernel_size=self.kernel_size, stride=self.stride, padding=self.padding) + ) + self.layers.append(nn.ReLU()) + for i in range(self.num_layers - 1): + # depthwise conv + self.layers.append( + nn.Conv2d( + self.channels, + self.channels, + kernel_size=self.kernel_size, + stride=self.stride, + padding=self.padding, + groups=self.channels, + ) + ) + # pointwise conv + self.layers.append(nn.Conv2d(self.channels, self.channels, kernel_size=1)) + # activation + self.layers.append(nn.ReLU()) + + out_length = config.num_mel_bins // (self.stride**self.num_layers) + self.linear = nn.Linear(config.subsampling_conv_channels * out_length, config.hidden_size, bias=True) + + def _get_output_length(self, input_lengths: torch.Tensor, conv_layer: nn.Conv2d): + if hasattr(conv_layer, "stride") and conv_layer.stride != (1, 1): + padding = conv_layer.padding + kernel_size = conv_layer.kernel_size[0] + stride = conv_layer.stride[0] + + output_lengths = (input_lengths + padding[0] + padding[1] - kernel_size) // stride + 1 + return output_lengths + + return input_lengths + + def forward(self, input_features: torch.Tensor, attention_mask: torch.Tensor = None): + hidden_states = input_features.unsqueeze(1) + current_lengths = attention_mask.sum(-1) if attention_mask is not None else None + + for layer in self.layers: + hidden_states = layer(hidden_states) + + # mask the hidden states + if isinstance(layer, nn.Conv2d) and attention_mask is not None: + current_lengths = self._get_output_length(current_lengths, layer) + current_seq_length = hidden_states.shape[2] + channel_mask = ( + torch.arange(current_seq_length, device=attention_mask.device) < current_lengths[:, None] + ) + hidden_states *= channel_mask[:, None, :, None] + + hidden_states = hidden_states.transpose(1, 2).reshape(hidden_states.shape[0], hidden_states.shape[2], -1) + hidden_states = self.linear(hidden_states) + + return hidden_states + + +class ParakeetEncoderBlock(GradientCheckpointingLayer): + def __init__(self, config: ParakeetEncoderConfig, layer_idx: int | None = None): + super().__init__() + self.gradient_checkpointing = False + + self.feed_forward1 = ParakeetEncoderFeedForward(config) + self.self_attn = ParakeetEncoderAttention(config, layer_idx) + self.conv = ParakeetEncoderConvolutionModule(config) + self.feed_forward2 = ParakeetEncoderFeedForward(config) + + self.norm_feed_forward1 = nn.LayerNorm(config.hidden_size) + self.norm_self_att = nn.LayerNorm(config.hidden_size) + self.norm_conv = nn.LayerNorm(config.hidden_size) + self.norm_feed_forward2 = nn.LayerNorm(config.hidden_size) + self.norm_out = nn.LayerNorm(config.hidden_size) + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.Tensor | None = None, + position_embeddings: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> torch.Tensor: + residual = hidden_states + hidden_states = self.feed_forward1(self.norm_feed_forward1(hidden_states)) + hidden_states = residual + 0.5 * hidden_states # the conformer architecture uses a factor of 0.5 + + normalized_hidden_states = self.norm_self_att(hidden_states) + attn_output, _ = self.self_attn( + hidden_states=normalized_hidden_states, + attention_mask=attention_mask, + position_embeddings=position_embeddings, + **kwargs, + ) + hidden_states = hidden_states + attn_output + + conv_output = self.conv(self.norm_conv(hidden_states), attention_mask=attention_mask) + hidden_states = hidden_states + conv_output + + ff2_output = self.feed_forward2(self.norm_feed_forward2(hidden_states)) + hidden_states = hidden_states + 0.5 * ff2_output # the conformer architecture uses a factor of 0.5 + + hidden_states = self.norm_out(hidden_states) + + return hidden_states + + +@auto_docstring +class ParakeetPreTrainedModel(PreTrainedModel): + config: ParakeetCTCConfig + base_model_prefix = "model" + main_input_name = "input_features" + input_modalities = "audio" + supports_gradient_checkpointing = True + _no_split_modules = ["ParakeetEncoderBlock"] + _supports_flat_attention_mask = True + _supports_sdpa = True + _supports_flex_attn = True + + # TODO: @eustlb, add support when flash attention supports custom attention bias + _supports_flash_attn = False + + _can_compile_fullgraph = True + _supports_attention_backend = True + _can_record_outputs = { + "hidden_states": ParakeetEncoderBlock, + "attentions": ParakeetEncoderAttention, + } + + @torch.no_grad() + def _init_weights(self, module): + super()._init_weights(module) + + if hasattr(self.config, "initializer_range"): + std = self.config.initializer_range + else: + # 0.02 is the standard default value across the library + std = getattr(self.config.get_text_config(), "initializer_range", 0.02) + + if isinstance(module, ParakeetEncoderAttention): + # Initialize positional bias parameters + init.normal_(module.bias_u, mean=0.0, std=std) + init.normal_(module.bias_v, mean=0.0, std=std) + elif isinstance(module, ParakeetEncoderRelPositionalEncoding): + inv_freq = 1.0 / ( + 10000.0 ** (torch.arange(0, self.config.hidden_size, 2, dtype=torch.int64) / self.config.hidden_size) + ) + init.copy_(module.inv_freq, inv_freq) + + def _get_subsampling_output_length(self, input_lengths: torch.Tensor): + encoder_config = self.config.encoder_config if isinstance(self.config, ParakeetCTCConfig) else self.config + + kernel_size = encoder_config.subsampling_conv_kernel_size + stride = encoder_config.subsampling_conv_stride + num_layers = int(math.log2(encoder_config.subsampling_factor)) + + all_paddings = (kernel_size - 1) // 2 * 2 + add_pad = all_paddings - kernel_size + lengths = input_lengths + + for _ in range(num_layers): + lengths = torch.div(lengths.to(dtype=torch.float) + add_pad, stride) + 1.0 + lengths = torch.floor(lengths) + + return lengths.to(dtype=torch.int) + + def _get_output_attention_mask(self, attention_mask: torch.Tensor, target_length: int | None = None): + """ + Convert the input attention mask to its subsampled form. `target_length` sets the desired output length, useful + when the attention mask length differs from `sum(-1).max()` (i.e., when the longest sequence in the batch is padded) + """ + output_lengths = self._get_subsampling_output_length(attention_mask.sum(-1)) + # Use target_length if provided, otherwise use max length in batch + max_length = target_length if target_length is not None else output_lengths.max() + attention_mask = torch.arange(max_length, device=attention_mask.device) < output_lengths[:, None] + return attention_mask + + +@auto_docstring( + custom_intro=""" + The Parakeet Encoder model, based on the [Fast Conformer architecture](https://huggingface.co/papers/2305.05084). + """ +) +class ParakeetEncoder(ParakeetPreTrainedModel): + config: ParakeetEncoderConfig + base_model_prefix = "encoder" + + def __init__(self, config: ParakeetEncoderConfig): + super().__init__(config) + self.config = config + self.gradient_checkpointing = False + + self.dropout = config.dropout + self.dropout_positions = config.dropout_positions + self.layerdrop = config.layerdrop + + self.input_scale = math.sqrt(config.hidden_size) if config.scale_input else 1.0 + self.subsampling = ParakeetEncoderSubsamplingConv2D(config) + self.encode_positions = ParakeetEncoderRelPositionalEncoding(config) + + self.layers = nn.ModuleList( + [ParakeetEncoderBlock(config, layer_idx) for layer_idx in range(config.num_hidden_layers)] + ) + + self.post_init() + + @auto_docstring + @merge_with_config_defaults + @capture_outputs + @can_return_tuple + def forward( + self, + input_features: torch.Tensor, + attention_mask: torch.Tensor | None = None, + output_attention_mask: bool | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> BaseModelOutput: + r""" + output_attention_mask (`bool`, *optional*): + Whether to return the output attention mask. + + Example: + + ```python + >>> from transformers import AutoProcessor, ParakeetEncoder + >>> from datasets import load_dataset, Audio + + >>> model_id = "nvidia/parakeet-ctc-1.1b" + >>> processor = AutoProcessor.from_pretrained(model_id) + >>> encoder = ParakeetEncoder.from_pretrained(model_id) + + >>> ds = load_dataset("hf-internal-testing/librispeech_asr_dummy", "clean", split="validation") + >>> ds = ds.cast_column("audio", Audio(sampling_rate=processor.feature_extractor.sampling_rate)) + + >>> inputs = processor(ds[0]["audio"]["array"]) + >>> encoder_outputs = encoder(**inputs) + + >>> print(encoder_outputs.last_hidden_state.shape) + ``` + """ + + hidden_states = self.subsampling(input_features, attention_mask) + hidden_states = hidden_states * self.input_scale + position_embeddings = self.encode_positions(hidden_states) + + hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training) + position_embeddings = nn.functional.dropout( + position_embeddings, p=self.dropout_positions, training=self.training + ) + + if attention_mask is not None: + output_mask = self._get_output_attention_mask(attention_mask, target_length=hidden_states.shape[1]) + attention_mask = output_mask.unsqueeze(1).expand(-1, hidden_states.shape[1], -1) + attention_mask = attention_mask & attention_mask.transpose(1, 2) + attention_mask = attention_mask.unsqueeze(1) + + for encoder_layer in self.layers: + # add LayerDrop (see https://huggingface.co/papers/1909.11556 for description) + to_drop = False + if self.training: + dropout_probability = torch.rand([]) + if dropout_probability < self.layerdrop: # skip the layer + to_drop = True + + if not to_drop: + hidden_states = encoder_layer( + hidden_states, + attention_mask=attention_mask, + position_embeddings=position_embeddings, + **kwargs, + ) + + return ParakeetEncoderModelOutput( + last_hidden_state=hidden_states, attention_mask=output_mask.int() if output_attention_mask else None + ) + + +@dataclass +class ParakeetGenerateOutput(ModelOutput): + """ + Outputs of Parakeet models. + + Args: + sequences (`torch.LongTensor` of shape `(batch_size, sequence_length)`): + The generated sequences. The second dimension (sequence_length) is either equal to `max_length` or shorter + if all batches finished early due to the `eos_token_id`. + logits (`tuple(torch.FloatTensor)` *optional*, returned when `output_logits=True`): + Unprocessed prediction scores of the language modeling head (scores for each vocabulary token before SoftMax) + at each generation step. Tuple of `torch.FloatTensor` with up to `max_new_tokens` elements (one element for + each generated token), with each tensor of shape `(batch_size, config.vocab_size)`. + attentions (`tuple(tuple(torch.FloatTensor))`, *optional*, returned when `output_attentions=True`): + Tuple (one element for each generated token) of tuples (one element for each layer of the decoder) of + `torch.FloatTensor` of shape `(batch_size, num_heads, generated_length, sequence_length)`. + hidden_states (`tuple(tuple(torch.FloatTensor))`, *optional*, returned when `output_hidden_states=True`): + Tuple (one element for each generated token) of tuples (one element for each layer of the decoder) of + `torch.FloatTensor` of shape `(batch_size, generated_length, hidden_size)`. + """ + + sequences: torch.LongTensor + logits: tuple[torch.FloatTensor] | None = None + attentions: tuple[tuple[torch.FloatTensor]] | None = None + hidden_states: tuple[tuple[torch.FloatTensor]] | None = None + + +@auto_docstring( + custom_intro=""" + Parakeet Encoder with a Connectionist Temporal Classification (CTC) head. + """ +) +class ParakeetForCTC(ParakeetPreTrainedModel): + config: ParakeetCTCConfig + + def __init__(self, config: ParakeetCTCConfig): + super().__init__(config) + self.encoder = ParakeetEncoder(config.encoder_config) + # Conv rather than linear to be consistent with NeMO decoding layer + self.ctc_head = nn.Conv1d(config.encoder_config.hidden_size, config.vocab_size, kernel_size=1) + + self.post_init() + + @auto_docstring + @can_return_tuple + def forward( + self, + input_features: torch.Tensor, + attention_mask: torch.Tensor | None = None, + labels: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> CausalLMOutput: + r""" + Example: + + ```python + >>> from transformers import AutoProcessor, ParakeetForCTC + >>> from datasets import load_dataset, Audio + + >>> model_id = "nvidia/parakeet-ctc-1.1b" + >>> processor = AutoProcessor.from_pretrained(model_id) + >>> model = ParakeetForCTC.from_pretrained(model_id) + + >>> ds = load_dataset("hf-internal-testing/librispeech_asr_dummy", "clean", split="validation") + >>> ds = ds.cast_column("audio", Audio(sampling_rate=processor.feature_extractor.sampling_rate)) + + >>> inputs = processor(ds[0]["audio"]["array"], text=ds[0]["text"]) + >>> outputs = model(**inputs) + + >>> print(outputs.loss) + ```""" + + encoder_outputs = self.encoder( + input_features=input_features, + attention_mask=attention_mask, + **kwargs, + ) + + hidden_states = encoder_outputs.last_hidden_state + logits = self.ctc_head(hidden_states.transpose(1, 2)).transpose(1, 2) + + loss = None + if labels is not None: + # retrieve loss input_lengths from attention_mask + attention_mask = ( + attention_mask if attention_mask is not None else torch.ones_like(input_features, dtype=torch.long) + ) + input_lengths = self._get_subsampling_output_length(attention_mask.sum(-1)) + + # assuming that padded tokens are filled with -100 + # when not being attended to + labels_mask = labels != self.config.pad_token_id + target_lengths = labels_mask.sum(-1) + flattened_targets = labels.masked_select(labels_mask) + + # ctc_loss doesn't support fp16 + log_probs = nn.functional.log_softmax(logits, dim=-1, dtype=torch.float32).transpose(0, 1) + + with torch.backends.cudnn.flags(enabled=False): + loss = nn.functional.ctc_loss( + log_probs, + flattened_targets, + input_lengths, + target_lengths, + blank=self.config.pad_token_id, + reduction=self.config.ctc_loss_reduction, + zero_infinity=self.config.ctc_zero_infinity, + ) + + return CausalLMOutput( + loss=loss, + logits=logits, + hidden_states=encoder_outputs.hidden_states, + attentions=encoder_outputs.attentions, + ) + + @torch.no_grad() + def generate( + self, + input_features: torch.Tensor, + attention_mask: torch.Tensor | None = None, + return_dict_in_generate: bool = False, + **kwargs: Unpack[TransformersKwargs], + ) -> ParakeetGenerateOutput | torch.LongTensor: + r""" + Example: + + ```python + >>> from transformers import AutoProcessor, ParakeetForCTC + >>> from datasets import load_dataset, Audio + + >>> model_id = "nvidia/parakeet-ctc-1.1b" + >>> processor = AutoProcessor.from_pretrained(model_id) + >>> model = ParakeetForCTC.from_pretrained(model_id) + + >>> ds = load_dataset("hf-internal-testing/librispeech_asr_dummy", "clean", split="validation") + >>> ds = ds.cast_column("audio", Audio(sampling_rate=processor.feature_extractor.sampling_rate)) + + >>> inputs = processor(ds[0]["audio"]["array"], text=ds[0]["text"]) + >>> predicted_ids = model.generate(**inputs) + >>> transcription = processor.batch_decode(predicted_ids, skip_special_tokens=True) + + >>> print(transcription) + ``` + """ + kwargs["return_dict"] = True + outputs: CausalLMOutput = self.forward( + input_features=input_features, + attention_mask=attention_mask, + **kwargs, + ) + + # greedy decoding + sequences = outputs.logits.argmax(dim=-1) + + # mask out padded tokens + if attention_mask is not None: + attention_mask = self._get_output_attention_mask(attention_mask, target_length=sequences.shape[1]) + sequences[~attention_mask] = self.config.pad_token_id + + if return_dict_in_generate: + return ParakeetGenerateOutput( + sequences=sequences, + logits=outputs.logits, + attentions=outputs.attentions, + hidden_states=outputs.hidden_states, + ) + + return sequences + + +__all__ = ["ParakeetForCTC", "ParakeetEncoder", "ParakeetPreTrainedModel"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/parakeet/processing_parakeet.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/parakeet/processing_parakeet.py new file mode 100644 index 0000000000000000000000000000000000000000..69734fb055afd0c72bbcd366dd61410d6cba37f4 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/parakeet/processing_parakeet.py @@ -0,0 +1,94 @@ +# Copyright 2025 The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +from ...audio_utils import AudioInput, make_list_of_audio +from ...processing_utils import ProcessingKwargs, ProcessorMixin, Unpack +from ...tokenization_utils_base import PreTokenizedInput, TextInput +from ...utils import auto_docstring, logging + + +logger = logging.get_logger(__name__) + + +class ParakeetProcessorKwargs(ProcessingKwargs, total=False): + _defaults = { + "audio_kwargs": { + "sampling_rate": 16000, + "padding": "longest", + "return_attention_mask": True, + }, + "text_kwargs": { + "padding": True, + "padding_side": "right", + "add_special_tokens": False, + }, + "common_kwargs": {"return_tensors": "pt"}, + } + + +@auto_docstring +class ParakeetProcessor(ProcessorMixin): + def __init__(self, feature_extractor, tokenizer): + super().__init__(feature_extractor, tokenizer) + + @auto_docstring + def __call__( + self, + audio: AudioInput, + text: TextInput | PreTokenizedInput | list[TextInput] | list[PreTokenizedInput] | None = None, + sampling_rate: int | None = None, + **kwargs: Unpack[ParakeetProcessorKwargs], + ): + r""" + sampling_rate (`int`, *optional*): + The sampling rate of the input audio in Hz. This should match the sampling rate expected by the feature + extractor (defaults to 16000 Hz). If provided, it will be validated against the processor's expected + sampling rate, and an error will be raised if they don't match. If not provided, a warning will be + issued and the default sampling rate will be assumed. + """ + audio = make_list_of_audio(audio) + + output_kwargs = self._merge_kwargs( + ParakeetProcessorKwargs, + tokenizer_init_kwargs=self.tokenizer.init_kwargs, + **kwargs, + ) + + if sampling_rate is None: + logger.warning_once( + f"You've provided audio without specifying the sampling rate. It will be assumed to be {output_kwargs['audio_kwargs']['sampling_rate']}, which can result in silent errors." + ) + elif sampling_rate != output_kwargs["audio_kwargs"]["sampling_rate"]: + raise ValueError( + f"The sampling rate of the audio ({sampling_rate}) does not match the sampling rate of the processor ({output_kwargs['audio_kwargs']['sampling_rate']}). Please provide resampled the audio to the expected sampling rate." + ) + + if audio is not None: + inputs = self.feature_extractor(audio, **output_kwargs["audio_kwargs"]) + if text is not None: + encodings = self.tokenizer(text, **output_kwargs["text_kwargs"]) + + if text is None: + return inputs + else: + inputs["labels"] = encodings["input_ids"] + return inputs + + @property + def model_input_names(self): + feature_extractor_input_names = self.feature_extractor.model_input_names + return feature_extractor_input_names + ["labels"] + + +__all__ = ["ParakeetProcessor"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/parakeet/tokenization_parakeet.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/parakeet/tokenization_parakeet.py new file mode 100644 index 0000000000000000000000000000000000000000..7b51885aef06818d63c47b7c1166c91046153793 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/parakeet/tokenization_parakeet.py @@ -0,0 +1,52 @@ +# Copyright 2025 The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import itertools + +from ...tokenization_utils_tokenizers import TokenizersBackend + + +class ParakeetTokenizer(TokenizersBackend): + """ + Inherits all methods from [`PreTrainedTokenizerFast`]. Users should refer to this superclass for more information regarding those methods, + except for `_decode` which is overridden to adapt it to CTC decoding: + 1. Group consecutive tokens + 2. Filter out the blank token + """ + + def _decode( + self, + token_ids: int | list[int], + skip_special_tokens: bool = False, + clean_up_tokenization_spaces: bool | None = None, + group_tokens: bool = True, + **kwargs, + ) -> str: + if isinstance(token_ids, int): + token_ids = [token_ids] + if group_tokens: + token_ids = [token_group[0] for token_group in itertools.groupby(token_ids)] + + # for CTC we filter out the blank token, which is the pad token + token_ids = [token for token in token_ids if token != self.pad_token_id] + + return super()._decode( + token_ids=token_ids, + skip_special_tokens=skip_special_tokens, + clean_up_tokenization_spaces=clean_up_tokenization_spaces, + **kwargs, + ) + + +__all__ = ["ParakeetTokenizer"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/patchtsmixer/__init__.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/patchtsmixer/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..285c1970308a47827806fca349d130703f40a2c8 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/patchtsmixer/__init__.py @@ -0,0 +1,27 @@ +# Copyright 2024 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from typing import TYPE_CHECKING + +from ...utils import _LazyModule +from ...utils.import_utils import define_import_structure + + +if TYPE_CHECKING: + from .configuration_patchtsmixer import * + from .modeling_patchtsmixer import * +else: + import sys + + _file = globals()["__file__"] + sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__) diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/patchtsmixer/configuration_patchtsmixer.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/patchtsmixer/configuration_patchtsmixer.py new file mode 100644 index 0000000000000000000000000000000000000000..a952f07b9d5a280f83381abbaca5bef6dbfbdbac --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/patchtsmixer/configuration_patchtsmixer.py @@ -0,0 +1,227 @@ +# Copyright 2023 IBM and HuggingFace Inc. team. All Rights Reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""PatchTSMixer model configuration""" + +from ...configuration_utils import PreTrainedConfig +from ...utils import logging + + +logger = logging.get_logger(__name__) + + +class PatchTSMixerConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`PatchTSMixerModel`]. It is used to instantiate a + PatchTSMixer model according to the specified arguments, defining the model architecture. Instantiating a + configuration with the defaults will yield a similar configuration to that of the PatchTSMixer + [ibm/patchtsmixer-etth1-pretrain](https://huggingface.co/ibm/patchtsmixer-etth1-pretrain) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + context_length (`int`, *optional*, defaults to 32): + The context/history length for the input sequence. + patch_length (`int`, *optional*, defaults to 8): + The patch length for the input sequence. + num_input_channels (`int`, *optional*, defaults to 1): + Number of input variates. For Univariate, set it to 1. + patch_stride (`int`, *optional*, defaults to 8): + Determines the overlap between two consecutive patches. Set it to patch_length (or greater), if we want + non-overlapping patches. + num_parallel_samples (`int`, *optional*, defaults to 100): + The number of samples to generate in parallel for probabilistic forecast. + d_model (`int`, *optional*, defaults to 8): + Hidden dimension of the model. Recommended to set it as a multiple of patch_length (i.e. 2-5X of + patch_length). Larger value indicates more complex model. + expansion_factor (`int`, *optional*, defaults to 2): + Expansion factor to use inside MLP. Recommended range is 2-5. Larger value indicates more complex model. + num_layers (`int`, *optional*, defaults to 3): + Number of layers to use. Recommended range is 3-15. Larger value indicates more complex model. + dropout (`float`, *optional*, defaults to 0.2): + The dropout probability the `PatchTSMixer` backbone. Recommended range is 0.2-0.7 + mode (`str`, *optional*, defaults to `"common_channel"`): + Mixer Mode. Determines how to process the channels. Allowed values: "common_channel", "mix_channel". In + "common_channel" mode, we follow Channel-independent modelling with no explicit channel-mixing. Channel + mixing happens in an implicit manner via shared weights across channels. (preferred first approach) In + "mix_channel" mode, we follow explicit channel-mixing in addition to patch and feature mixer. (preferred + approach when channel correlations are very important to model) + gated_attn (`bool`, *optional*, defaults to `True`): + Enable Gated Attention. + norm_mlp (`str`, *optional*, defaults to `"LayerNorm"`): + Normalization layer (BatchNorm or LayerNorm). + self_attn (`bool`, *optional*, defaults to `False`): + Enable Tiny self attention across patches. This can be enabled when the output of Vanilla PatchTSMixer with + gated attention is not satisfactory. Enabling this leads to explicit pair-wise attention and modelling + across patches. + self_attn_heads (`int`, *optional*, defaults to 1): + Number of self-attention heads. Works only when `self_attn` is set to `True`. + use_positional_encoding (`bool`, *optional*, defaults to `False`): + Enable the use of positional embedding for the tiny self-attention layers. Works only when `self_attn` is + set to `True`. + positional_encoding_type (`str`, *optional*, defaults to `"sincos"`): + Positional encodings. Options `"random"` and `"sincos"` are supported. Works only when + `use_positional_encoding` is set to `True` + scaling (`string` or `bool`, *optional*, defaults to `"std"`): + Whether to scale the input targets via "mean" scaler, "std" scaler or no scaler if `None`. If `True`, the + scaler is set to "mean". + loss (`string`, *optional*, defaults to `"mse"`): + The loss function for the model corresponding to the `distribution_output` head. For parametric + distributions it is the negative log likelihood ("nll") and for point estimates it is the mean squared + error "mse". + init_std (`float`, *optional*, defaults to 0.02): + The standard deviation of the truncated normal weight initialization distribution. + norm_eps (`float`, *optional*, defaults to 1e-05): + A value added to the denominator for numerical stability of normalization. + mask_type (`str`, *optional*, defaults to `"random"`): + Type of masking to use for Masked Pretraining mode. Allowed values are "random", "forecast". In Random + masking, points are masked randomly. In Forecast masking, points are masked towards the end. + random_mask_ratio (`float`, *optional*, defaults to 0.5): + Masking ratio to use when `mask_type` is `random`. Higher value indicates more masking. + num_forecast_mask_patches (`int` or `list`, *optional*, defaults to `[2]`): + Number of patches to be masked at the end of each batch sample. If it is an integer, all the samples in the + batch will have the same number of masked patches. If it is a list, samples in the batch will be randomly + masked by numbers defined in the list. This argument is only used for forecast pretraining. + mask_value (`float`, *optional*, defaults to `0.0`): + Mask value to use. + masked_loss (`bool`, *optional*, defaults to `True`): + Whether to compute pretraining loss only at the masked portions, or on the entire output. + channel_consistent_masking (`bool`, *optional*, defaults to `True`): + When true, masking will be same across all channels of a timeseries. Otherwise, masking positions will vary + across channels. + unmasked_channel_indices (`list`, *optional*): + Channels that are not masked during pretraining. + head_dropout (`float`, *optional*, defaults to 0.2): + The dropout probability the `PatchTSMixer` head. + distribution_output (`string`, *optional*, defaults to `"student_t"`): + The distribution emission head for the model when loss is "nll". Could be either "student_t", "normal" or + "negative_binomial". + prediction_length (`int`, *optional*, defaults to 16): + Number of time steps to forecast for a forecasting task. Also known as the Forecast Horizon. + prediction_channel_indices (`list`, *optional*): + List of channel indices to forecast. If None, forecast all channels. Target data is expected to have all + channels and we explicitly filter the channels in prediction and target before loss computation. + num_targets (`int`, *optional*, defaults to 3): + Number of targets (dimensionality of the regressed variable) for a regression task. + output_range (`list`, *optional*): + Output range to restrict for the regression task. Defaults to None. + head_aggregation (`str`, *optional*, defaults to `"max_pool"`): + Aggregation mode to enable for classification or regression task. Allowed values are `None`, "use_last", + "max_pool", "avg_pool". + + Example: + + ```python + >>> from transformers import PatchTSMixerConfig, PatchTSMixerModel + + >>> # Initializing a default PatchTSMixer configuration + >>> configuration = PatchTSMixerConfig() + + >>> # Randomly initializing a model (with random weights) from the configuration + >>> model = PatchTSMixerModel(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "patchtsmixer" + attribute_map = { + "hidden_size": "d_model", + "num_hidden_layers": "num_layers", + } + + def __init__( + self, + # Time series specific configuration + context_length: int = 32, + patch_length: int = 8, + num_input_channels: int = 1, + patch_stride: int = 8, + num_parallel_samples: int = 100, + # General model configuration + d_model: int = 8, + expansion_factor: int = 2, + num_layers: int = 3, + dropout: float = 0.2, + mode: str = "common_channel", + gated_attn: bool = True, + norm_mlp: str = "LayerNorm", + self_attn: bool = False, + self_attn_heads: int = 1, + use_positional_encoding: bool = False, + positional_encoding_type: str = "sincos", + scaling: str | bool | None = "std", + loss: str = "mse", + init_std: float = 0.02, + norm_eps: float = 1e-5, + # Pretrain model configuration + mask_type: str = "random", + random_mask_ratio: float = 0.5, + num_forecast_mask_patches: list[int] | int | None = [2], + mask_value: int = 0, + masked_loss: bool = True, + channel_consistent_masking: bool = True, + unmasked_channel_indices: list[int] | None = None, + # General head configuration + head_dropout: float = 0.2, + distribution_output: str = "student_t", + # Prediction head configuration + prediction_length: int = 16, + prediction_channel_indices: list | None = None, + # Classification/Regression configuration + num_targets: int = 3, + output_range: list | None = None, + head_aggregation: str = "max_pool", + **kwargs, + ): + self.num_input_channels = num_input_channels + self.context_length = context_length + self.patch_length = patch_length + self.patch_stride = patch_stride + self.d_model = d_model + self.expansion_factor = expansion_factor + self.num_layers = num_layers + self.dropout = dropout + self.mode = mode + self.gated_attn = gated_attn + self.norm_mlp = norm_mlp + self.scaling = scaling + self.head_dropout = head_dropout + self.num_patches = (max(context_length, patch_length) - patch_length) // patch_stride + 1 + self.mask_type = mask_type + self.random_mask_ratio = random_mask_ratio + self.num_forecast_mask_patches = num_forecast_mask_patches + self.mask_value = mask_value + self.channel_consistent_masking = channel_consistent_masking + self.masked_loss = masked_loss + self.patch_last = True + self.use_positional_encoding = use_positional_encoding + self.positional_encoding_type = positional_encoding_type + self.prediction_length = prediction_length + self.prediction_channel_indices = prediction_channel_indices + self.num_targets = num_targets + self.output_range = output_range + self.head_aggregation = head_aggregation + self.self_attn = self_attn + self.self_attn_heads = self_attn_heads + self.init_std = init_std + self.distribution_output = distribution_output + self.loss = loss + self.num_parallel_samples = num_parallel_samples + self.unmasked_channel_indices = unmasked_channel_indices + self.norm_eps = norm_eps + super().__init__(**kwargs) + + +__all__ = ["PatchTSMixerConfig"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/patchtsmixer/modeling_patchtsmixer.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/patchtsmixer/modeling_patchtsmixer.py new file mode 100644 index 0000000000000000000000000000000000000000..4ceaaa1f66472e122dad2ffabb85e6acea897a43 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/patchtsmixer/modeling_patchtsmixer.py @@ -0,0 +1,2122 @@ +# Copyright 2023 IBM and HuggingFace Inc. team. All Rights Reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""PyTorch PatchTSMixer model.""" + +import math +from collections.abc import Callable +from dataclasses import dataclass + +import torch +import torch.nn as nn + +from transformers.modeling_utils import PreTrainedModel +from transformers.utils import ModelOutput + +from ... import initialization as init +from ...modeling_flash_attention_utils import FlashAttentionKwargs +from ...modeling_utils import ALL_ATTENTION_FUNCTIONS +from ...processing_utils import Unpack +from ...time_series_utils import NegativeBinomialOutput, NormalOutput, StudentTOutput +from ...utils import TransformersKwargs, auto_docstring, logging +from .configuration_patchtsmixer import PatchTSMixerConfig + + +logger = logging.get_logger(__name__) + + +class PatchTSMixerGatedAttention(nn.Module): + """ + Module that applies gated attention to input data. + + Args: + in_size (`int`): The input size. + out_size (`int`): The output size. + """ + + def __init__(self, in_size: int, out_size: int): + super().__init__() + self.attn_layer = nn.Linear(in_size, out_size) + self.attn_softmax = nn.Softmax(dim=-1) + + def forward(self, inputs): + attn_weight = self.attn_softmax(self.attn_layer(inputs)) + inputs = inputs * attn_weight + return inputs + + +# Copied from transformers.models.patchtst.modeling_patchtst.PatchTSTBatchNorm with PatchTST->PatchTSMixer +class PatchTSMixerBatchNorm(nn.Module): + """ + Compute batch normalization over the sequence length (time) dimension. + """ + + def __init__(self, config: PatchTSMixerConfig): + super().__init__() + self.batchnorm = nn.BatchNorm1d(config.d_model, eps=config.norm_eps) + + def forward(self, inputs: torch.Tensor): + """ + Parameters: + inputs (`torch.Tensor` of shape `(batch_size, sequence_length, d_model)`): + input for Batch norm calculation + Returns: + `torch.Tensor` of shape `(batch_size, sequence_length, d_model)` + """ + output = inputs.transpose(1, 2) # output: (batch_size, d_model, sequence_length) + output = self.batchnorm(output) + return output.transpose(1, 2) + + +class PatchTSMixerPositionalEncoding(nn.Module): + """ + Class for positional encoding + """ + + def __init__(self, config: PatchTSMixerConfig): + super().__init__() + # positional encoding: [num_patches x d_model] + if config.use_positional_encoding: + self.position_enc = self._init_pe(config) + else: + self.position_enc = nn.Parameter(torch.zeros(config.num_patches, config.d_model)) + + @staticmethod + def _init_pe(config: PatchTSMixerConfig) -> nn.Parameter: + # Positional encoding + if config.positional_encoding_type == "random": + position_enc = nn.Parameter(torch.randn(config.num_patches, config.d_model), requires_grad=True) + elif config.positional_encoding_type == "sincos": + position_enc = torch.zeros(config.num_patches, config.d_model) + position = torch.arange(0, config.num_patches).unsqueeze(1) + div_term = torch.exp(torch.arange(0, config.d_model, 2) * -(math.log(10000.0) / config.d_model)) + position_enc[:, 0::2] = torch.sin(position * div_term) + position_enc[:, 1::2] = torch.cos(position * div_term) + position_enc = position_enc - position_enc.mean() + position_enc = position_enc / (position_enc.std() * 10) + position_enc = nn.Parameter(position_enc, requires_grad=False) + else: + raise ValueError( + f"{config.positional_encoding_type} is not a valid positional encoder. Available types are 'random' and 'sincos'." + ) + return position_enc + + def forward(self, patch_input: torch.Tensor): + # hidden_state: [bs x num_channels x num_patches x d_model] + hidden_state = patch_input + self.position_enc + return hidden_state + + +class PatchTSMixerNormLayer(nn.Module): + """Normalization block + + Args: + config (`PatchTSMixerConfig`): + Configuration. + """ + + def __init__(self, config: PatchTSMixerConfig): + super().__init__() + + self.norm_mlp = config.norm_mlp + + if "batch" in config.norm_mlp.lower(): + self.norm = PatchTSMixerBatchNorm(config) + else: + self.norm = nn.LayerNorm(config.d_model, eps=config.norm_eps) + + def forward(self, inputs: torch.Tensor): + """ + Args: + inputs (`torch.Tensor` of shape `((batch_size, num_channels, num_patches, d_model))`): + Input to the normalization layer. + Returns: + `torch.Tensor` of shape `((batch_size, num_channels, num_patches, d_model))` + """ + if "batch" in self.norm_mlp.lower(): + # reshape the data + inputs_reshaped = torch.reshape( + inputs, + ( + inputs.shape[0] * inputs.shape[1], + inputs.shape[2], + inputs.shape[3], + ), + ) # inputs_reshaped: [batch_size*num_channels, num_patches, d_model] + + # inputs_reshaped: [batch_size*num_channels, num_patches, d_model] + inputs_reshaped = self.norm(inputs_reshaped) + + # put back data to the original shape + inputs = torch.reshape(inputs_reshaped, inputs.shape) + + else: + inputs = self.norm(inputs) + + return inputs + + +class PatchTSMixerMLP(nn.Module): + def __init__(self, in_features, out_features, config): + super().__init__() + num_hidden = in_features * config.expansion_factor + self.fc1 = nn.Linear(in_features, num_hidden) + self.dropout1 = nn.Dropout(config.dropout) + self.fc2 = nn.Linear(num_hidden, out_features) + self.dropout2 = nn.Dropout(config.dropout) + + def forward(self, inputs: torch.Tensor): + """ + Args: + inputs (`torch.Tensor` of shape `((batch_size, num_channels, num_patches, d_model))`): + Input to the MLP layer. + Returns: + `torch.Tensor` of the same shape as `inputs` + """ + inputs = self.dropout1(nn.functional.gelu(self.fc1(inputs))) + inputs = self.fc2(inputs) + inputs = self.dropout2(inputs) + return inputs + + +class PatchTSMixerChannelFeatureMixerBlock(nn.Module): + """This module mixes the features in the channel dimension. + + Args: + config (`PatchTSMixerConfig`): + Configuration. + """ + + def __init__(self, config: PatchTSMixerConfig): + super().__init__() + + self.norm = PatchTSMixerNormLayer(config) + self.gated_attn = config.gated_attn + self.mlp = PatchTSMixerMLP( + in_features=config.num_input_channels, + out_features=config.num_input_channels, + config=config, + ) + + if config.gated_attn: + self.gating_block = PatchTSMixerGatedAttention( + in_size=config.num_input_channels, out_size=config.num_input_channels + ) + + def forward(self, inputs: torch.Tensor): + """ + Args: + inputs (`torch.Tensor` of shape `((batch_size, num_channels, num_patches, d_model))`): + input to the MLP layer + Returns: + `torch.Tensor` of the same shape as `inputs` + """ + residual = inputs + inputs = self.norm(inputs) + + inputs = inputs.permute(0, 3, 2, 1) + + if self.gated_attn: + inputs = self.gating_block(inputs) + + inputs = self.mlp(inputs) + + inputs = inputs.permute(0, 3, 2, 1) + + out = inputs + residual + return out + + +# Copied from transformers.models.bert.modeling_bert.eager_attention_forward +def eager_attention_forward( + module: nn.Module, + query: torch.Tensor, + key: torch.Tensor, + value: torch.Tensor, + attention_mask: torch.Tensor | None, + scaling: float | None = None, + dropout: float = 0.0, + **kwargs: Unpack[TransformersKwargs], +): + if scaling is None: + scaling = query.size(-1) ** -0.5 + + # Take the dot product between "query" and "key" to get the raw attention scores. + attn_weights = torch.matmul(query, key.transpose(2, 3)) * scaling + + if attention_mask is not None: + attn_weights = attn_weights + attention_mask + + attn_weights = nn.functional.softmax(attn_weights, dim=-1) + attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training) + + attn_output = torch.matmul(attn_weights, value) + attn_output = attn_output.transpose(1, 2).contiguous() + + return attn_output, attn_weights + + +# Copied from transformers.models.wav2vec2.modeling_wav2vec2.Wav2Vec2Attention with Wav2Vec2->PatchTSMixer +class PatchTSMixerAttention(nn.Module): + """Multi-headed attention from 'Attention Is All You Need' paper""" + + def __init__( + self, + embed_dim: int, + num_heads: int, + dropout: float = 0.0, + is_decoder: bool = False, + bias: bool = True, + is_causal: bool = False, + config: PatchTSMixerConfig | None = None, + ): + super().__init__() + self.embed_dim = embed_dim + self.num_heads = num_heads + self.dropout = dropout + self.head_dim = embed_dim // num_heads + self.config = config + + if (self.head_dim * num_heads) != self.embed_dim: + raise ValueError( + f"embed_dim must be divisible by num_heads (got `embed_dim`: {self.embed_dim}" + f" and `num_heads`: {num_heads})." + ) + self.scaling = self.head_dim**-0.5 + self.is_decoder = is_decoder + self.is_causal = is_causal + + self.k_proj = nn.Linear(embed_dim, embed_dim, bias=bias) + self.v_proj = nn.Linear(embed_dim, embed_dim, bias=bias) + self.q_proj = nn.Linear(embed_dim, embed_dim, bias=bias) + self.out_proj = nn.Linear(embed_dim, embed_dim, bias=bias) + + def forward( + self, + hidden_states: torch.Tensor, + key_value_states: torch.Tensor | None = None, + attention_mask: torch.Tensor | None = None, + output_attentions: bool | None = False, + # TODO: we need a refactor so that the different attention modules can get their specific kwargs + # ATM, we have mixed things encoder, decoder, and encoder-decoder attn + **kwargs: Unpack[FlashAttentionKwargs], + ) -> tuple[torch.Tensor, torch.Tensor | None, tuple[torch.Tensor] | None]: + """Input shape: Batch x Time x Channel""" + + # if key_value_states are provided this layer is used as a cross-attention layer + # for the decoder + is_cross_attention = key_value_states is not None + + # determine input shapes + bsz, tgt_len = hidden_states.shape[:-1] + src_len = key_value_states.shape[1] if is_cross_attention else tgt_len + + q_input_shape = (bsz, tgt_len, -1, self.head_dim) + kv_input_shape = (bsz, src_len, -1, self.head_dim) + + # get query proj + query_states = self.q_proj(hidden_states).view(*q_input_shape).transpose(1, 2) + + current_states = key_value_states if is_cross_attention else hidden_states + key_states = self.k_proj(current_states).view(*kv_input_shape).transpose(1, 2) + value_states = self.v_proj(current_states).view(*kv_input_shape).transpose(1, 2) + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, eager_attention_forward + ) + + attn_output, attn_weights = attention_interface( + self, + query_states, + key_states, + value_states, + attention_mask, + dropout=0.0 if not self.training else self.dropout, + scaling=self.scaling, + output_attentions=output_attentions, + **kwargs, + ) + + attn_output = attn_output.reshape(bsz, tgt_len, -1).contiguous() + attn_output = self.out_proj(attn_output) + + return attn_output, attn_weights, None + + +class PatchMixerBlock(nn.Module): + """This module mixes the patch dimension. + + Args: + config (`PatchTSMixerConfig`): + Configuration. + """ + + def __init__(self, config: PatchTSMixerConfig): + super().__init__() + + self.norm = PatchTSMixerNormLayer(config) + + self.self_attn = config.self_attn + self.gated_attn = config.gated_attn + + self.mlp = PatchTSMixerMLP( + in_features=config.num_patches, + out_features=config.num_patches, + config=config, + ) + + if config.gated_attn: + self.gating_block = PatchTSMixerGatedAttention(in_size=config.num_patches, out_size=config.num_patches) + + if config.self_attn: + self.self_attn_layer = PatchTSMixerAttention( + embed_dim=config.d_model, + num_heads=config.self_attn_heads, + dropout=config.dropout, + config=config, + ) + self.norm_attn = PatchTSMixerNormLayer(config) + + def forward(self, hidden_state): + """ + Args: + hidden_state (`torch.Tensor`): Input tensor. + + Returns: + `torch.Tensor`: Transformed tensor. + """ + residual = hidden_state + + hidden_state = self.norm(hidden_state) + + if self.self_attn: + batch_size, n_vars, num_patches, d_model = hidden_state.shape + hidden_state_reshaped = hidden_state.reshape(batch_size * n_vars, num_patches, d_model) + + x_attn, _, _ = self.self_attn_layer(hidden_state_reshaped, output_attentions=False) + x_attn = x_attn.reshape(batch_size, n_vars, num_patches, d_model) + + # Transpose so that num_patches is the last dimension + hidden_state = hidden_state.transpose(2, 3) + hidden_state = self.mlp(hidden_state) + + if self.gated_attn: + hidden_state = self.gating_block(hidden_state) + + # Transpose back + hidden_state = hidden_state.transpose(2, 3) + + if self.self_attn: + hidden_state = self.norm_attn(hidden_state + x_attn) + + out = hidden_state + residual + return out + + +class FeatureMixerBlock(nn.Module): + """This module mixes the hidden feature dimension. + + Args: + config (`PatchTSMixerConfig`): + Configuration. + + """ + + def __init__(self, config: PatchTSMixerConfig): + super().__init__() + + self.norm = PatchTSMixerNormLayer(config) + + self.gated_attn = config.gated_attn + + self.mlp = PatchTSMixerMLP( + in_features=config.d_model, + out_features=config.d_model, + config=config, + ) + + if config.gated_attn: + self.gating_block = PatchTSMixerGatedAttention(in_size=config.d_model, out_size=config.d_model) + + def forward(self, hidden: torch.Tensor): + """ + Args: + hidden (`torch.Tensor` of shape `(batch_size, num_patches, d_model)`): + Input tensor to the layer. + + Returns: + `torch.Tensor`: Transformed tensor. + """ + residual = hidden + hidden = self.norm(hidden) + hidden = self.mlp(hidden) + + if self.gated_attn: + hidden = self.gating_block(hidden) + + out = hidden + residual + return out + + +class PatchTSMixerLayer(nn.Module): + """ + The `PatchTSMixer` layer that does all three kinds of mixing. + + Args: + config (`PatchTSMixerConfig`): + Configuration. + + """ + + def __init__(self, config: PatchTSMixerConfig): + super().__init__() + + self.patch_mixer = PatchMixerBlock(config=config) + self.feature_mixer = FeatureMixerBlock(config=config) + + self.mode = config.mode + + if config.mode == "mix_channel": + self.channel_feature_mixer = PatchTSMixerChannelFeatureMixerBlock(config=config) + + def forward(self, hidden: torch.Tensor): + """ + Args: + hidden (`torch.Tensor` of shape `(batch_size, num_patches, d_model)`): + Input tensor to the layer. + + Returns: + `torch.Tensor`: Transformed tensor. + """ + if self.mode == "mix_channel": + hidden = self.channel_feature_mixer(hidden) + + hidden = self.patch_mixer(hidden) + hidden = self.feature_mixer(hidden) # hidden: (batch_size x num_patches x d_model) + return hidden + + +class PatchTSMixerBlock(nn.Module): + """The main computing framework of the `PatchTSMixer` model. + + Args: + config (`PatchTSMixerConfig`): + Configuration. + """ + + def __init__(self, config: PatchTSMixerConfig): + super().__init__() + + num_layers = config.num_layers + + self.mixers = nn.ModuleList([PatchTSMixerLayer(config=config) for _ in range(num_layers)]) + + def forward(self, hidden_state, output_hidden_states: bool = False): + """ + Args: + hidden_state (`torch.Tensor`): The input tensor. + output_hidden_states (`bool`, *optional*, defaults to False.): + Whether to output the hidden states as well. + + Returns: + `torch.Tensor`: The embedding. `list`: List of all hidden states if `output_hidden_states` is set to + `True`. + """ + all_hidden_states = [] + + embedding = hidden_state + + for mod in self.mixers: + embedding = mod(embedding) + if output_hidden_states: + all_hidden_states.append(embedding) + + if output_hidden_states: + return embedding, all_hidden_states + else: + return embedding, None + + +class PatchTSMixerForPredictionHead(nn.Module): + """Prediction Head for Forecasting + + Args: + config (`PatchTSMixerConfig`): + Configuration. + """ + + def __init__(self, config: PatchTSMixerConfig, distribution_output=None): + super().__init__() + + self.prediction_channel_indices = config.prediction_channel_indices + + if self.prediction_channel_indices is not None: + self.prediction_channel_indices.sort() + + self.dropout_layer = nn.Dropout(config.head_dropout) + if distribution_output is None: + self.base_forecast_block = nn.Linear((config.num_patches * config.d_model), config.prediction_length) + else: + self.base_forecast_block = distribution_output.get_parameter_projection( + config.num_patches * config.d_model + ) + + self.flatten = nn.Flatten(start_dim=-2) + + def forward(self, hidden_features): + """ + + Args: + hidden_features (`torch.Tensor` of shape `(batch_size, num_patch, d_model)` in `flatten` mode + or `(batch_size, n_vars, num_patch, d_model)` in `common_channel`/`mix_channel` mode.): Input hidden + features. + + Returns: + `torch.Tensor` of shape `(batch_size, prediction_length, nvars)`. + + """ + + hidden_features = self.flatten(hidden_features) # [batch_size x n_vars x num_patch * d_model] + hidden_features = self.dropout_layer(hidden_features) # [batch_size x n_vars x num_patch * d_model] + forecast = self.base_forecast_block(hidden_features) # [batch_size x n_vars x prediction_length] + if isinstance(forecast, tuple): + forecast = tuple(z.transpose(-1, -2) for z in forecast) + else: + forecast = forecast.transpose(-1, -2) # [batch_size x prediction_length x n_vars] + + if self.prediction_channel_indices is not None: + if isinstance(forecast, tuple): + forecast = tuple(z[..., self.prediction_channel_indices] for z in forecast) + else: + forecast = forecast[..., self.prediction_channel_indices] # [batch_size x prediction_length x n_vars] + + return forecast + + +class PatchTSMixerLinearHead(nn.Module): + """Linear head for Classification and Regression. + + Args: + config (`PatchTSMixerConfig`): + Configuration. + """ + + def __init__(self, config: PatchTSMixerConfig, distribution_output=None): + super().__init__() + + self.head_aggregation = config.head_aggregation + self.output_range = config.output_range + + if config.head_aggregation is None: + mul_factor = config.num_patches + else: + mul_factor = 1 + self.distribution_output = distribution_output + if distribution_output is None: + self.projection = nn.Linear( + config.d_model * config.num_input_channels * mul_factor, + config.num_targets, + ) + else: + self.projection = distribution_output.get_parameter_projection( + config.d_model * config.num_input_channels * mul_factor + ) + + if config.head_aggregation is None: + self.flatten = nn.Flatten(start_dim=-3) + else: + self.flatten = nn.Flatten(start_dim=-2) + + self.dropout = nn.Dropout(config.head_dropout) + + def forward(self, hidden_features): + """ + Args: + hidden_features (`torch.Tensor` of shape `(batch_size x num_patch x d_model)` in `flatten` mode + or `(batch_size x n_vars x num_patch x d_model)` in `common_channel`/`mix_channel` mode.): Input hidden + features. + + Returns: + `torch.Tensor` of shape `(batch_size x num_targets)`. + """ + + # batch_size x d_model x num_patch or batch_size x n_vars x d_model x num_patch + hidden_features = hidden_features.transpose(-1, -2) + if self.head_aggregation == "use_last": + # batch_size x d_model (flatten) or # batch_size x n_vars x d_model (common_channel) + hidden_features = hidden_features[..., -1] + elif self.head_aggregation == "max_pool": + # batch_size x n_vars x d_model or batch_size x d_model + hidden_features = hidden_features.max(dim=-1).values + elif self.head_aggregation == "avg_pool": + # batch_size x n_vars x d_model or batch_size x d_model + hidden_features = hidden_features.mean(dim=-1) + + if self.flatten: + hidden_features = self.flatten(hidden_features) + hidden_features = self.dropout(hidden_features) + hidden_features = self.projection(hidden_features) # batch_size x num_targets + + if (self.distribution_output is None) and (self.output_range is not None): + hidden_features = ( + torch.sigmoid(hidden_features) * (self.output_range[1] - self.output_range[0]) + self.output_range[0] + ) + return hidden_features + + +@auto_docstring +class PatchTSMixerPreTrainedModel(PreTrainedModel): + # Weight initialization + config: PatchTSMixerConfig + base_model_prefix = "model" + main_input_name = "past_values" + input_modalities = ("time",) + supports_gradient_checkpointing = False + + @torch.no_grad() + def _init_weights(self, module): + """Initialize weights""" + if isinstance(module, PatchTSMixerPositionalEncoding): + # initialize positional encoding + if self.config.positional_encoding_type == "random": + init.normal_(module.position_enc, mean=0.0, std=0.1) + elif isinstance(module, (nn.LayerNorm, nn.BatchNorm1d)): + init.zeros_(module.bias) + init.ones_(module.weight) + if getattr(module, "running_mean", None) is not None: + init.zeros_(module.running_mean) + init.ones_(module.running_var) + init.zeros_(module.num_batches_tracked) + elif isinstance(module, PatchTSMixerBatchNorm): + init.zeros_(module.batchnorm.bias) + init.ones_(module.batchnorm.weight) + elif isinstance(module, nn.Linear): + init.normal_(module.weight, mean=0.0, std=self.config.init_std) + if module.bias is not None: + init.zeros_(module.bias) + + +class PatchTSMixerPretrainHead(nn.Module): + """Pretraining head. + + Args: + config (`PatchTSMixerConfig`): + Configuration. + """ + + def __init__(self, config: PatchTSMixerConfig): + super().__init__() + + self.dropout_layer = nn.Dropout(config.head_dropout) + self.base_pt_block = nn.Linear(config.d_model, config.patch_length) + + def forward(self, hidden_features): + """ + Args: + hidden_features (`torch.Tensor` of shape `(batch_size x num_patch x d_model)` in `flatten` mode + or `(batch_size x n_vars x num_patch x d_model)` in `common_channel`/`mix_channel` mode.): Input hidden + features. + + Returns: + `torch.Tensor` of shape `(batch_size x n_vars x num_patch x patch_length)`. + """ + + hidden_features = self.dropout_layer(hidden_features) + forecast = self.base_pt_block(hidden_features) # [batch_size x n_vars x num_patch x patch_length] + return forecast + + +# Copied from transformers.models.patchtst.modeling_patchtst.random_masking +def random_masking( + inputs: torch.Tensor, + mask_ratio: float, + unmasked_channel_indices: list | None = None, + channel_consistent_masking: bool = False, + mask_value: int = 0, +): + """random_masking: Mask the input considering the control variables. + + Args: + inputs (`torch.Tensor` of shape `(batch_size, num_channels, sequence_length, num_features)`): + The input tensor to mask. + mask_ratio (`float`): + Masking ratio applied to mask the input data during random pretraining. It is the number between 0 and 1. + unmasked_channel_indices (list, *optional*): + Indices of channels that will not be masked. + channel_consistent_masking (bool, *optional*, defaults to `False`): + When true, masking will be same across all channels of a timeseries. Otherwise, masking positions will vary + across channels. + mask_value (int, *optional*, defaults to 0): + Define the value of masked patches for pretraining. + + Returns: + `tuple(torch.Tensor)`: inputs_mask, masked input, same shape as input Tensor and mask tensor of shape [bs x c x + n] + """ + if mask_ratio < 0 or mask_ratio >= 1: + raise ValueError(f"Mask ratio {mask_ratio} has to be between 0 and 1.") + + batch_size, num_channels, sequence_length, num_features = inputs.shape + device = inputs.device + + len_keep = int(sequence_length * (1 - mask_ratio)) + + if channel_consistent_masking: + noise = torch.rand(batch_size, 1, sequence_length, device=device) # noise in [0, 1], bs x 1 x L + noise = noise.repeat(1, num_channels, 1) # bs x num_channels x time + else: + # noise in [0, 1], bs x num_channels x L + noise = torch.rand(batch_size, num_channels, sequence_length, device=device) + + # mask: [bs x num_channels x num_patch] + mask = torch.ones(batch_size, num_channels, sequence_length, device=device) + mask[:, :, :len_keep] = 0 + + # sort noise for each sample + ids_shuffle = torch.argsort(noise, dim=-1) # ascend: small is keep, large is remove + ids_restore = torch.argsort(ids_shuffle, dim=-1) # ids_restore: [bs x num_channels x L] + + mask = torch.gather(mask, dim=-1, index=ids_restore) + mask = mask.unsqueeze(-1).repeat(1, 1, 1, num_features) # mask: [bs x num_channels x num_patches x patch_length] + if unmasked_channel_indices is not None: + mask[:, unmasked_channel_indices, :, :] = 0 + + inputs_mask = inputs.masked_fill(mask.bool(), mask_value) + return inputs_mask, mask[..., 0] + + +# Copied from transformers.models.patchtst.modeling_patchtst.forecast_masking +def forecast_masking( + inputs: torch.Tensor, + num_forecast_mask_patches: list | int, + unmasked_channel_indices: list | None = None, + mask_value: int = 0, +): + """Forecast masking that masks the last K patches where K is from the num_forecast_mask_patches. + If num_forecast_mask_patches is a list, samples in the batch will be randomly masked by numbers defined in the list. + + Parameters: + inputs (`torch.Tensor`): + Input of shape `(bs, num_channels, num_patch, patch_length)` + num_forecast_mask_patches (`list`): + Number of patches to be masked at the end of each batch sample. e.g. 4 or [3, 5]. + unmasked_channel_indices (`list`, *optional*): + Indices of channels that are not masked. + mask_value (`int`, *optional*, defaults to 0): + Values in the masked patches will be filled by `mask_value`. + + Returns: + `tuple(torch.Tensor)`: inputs_mask, masked input, same shape as inputs Tensor and Mask tensor of shape `(bs, + num_channels , num_patch)` or `(bs, tsg1, tsg2, num_channels, num_patch)` + """ + + if isinstance(num_forecast_mask_patches, int): + num_forecast_mask_patches = [num_forecast_mask_patches] + forecast_mask_ratios = [1 for _ in num_forecast_mask_patches] + + batch_size, num_channels, sequence_length, num_features = inputs.shape + mask = torch.zeros(batch_size, num_channels, sequence_length, device=inputs.device) + + t_list = [] + total_length = 0 + total_ratio = sum(forecast_mask_ratios) + + for patch_length, ratio in zip(num_forecast_mask_patches, forecast_mask_ratios): + if patch_length <= 0 or patch_length >= sequence_length: + raise ValueError( + f"num_forecast_mask_patches {patch_length} should be greater than 0 and less than total patches." + ) + temp_len = int(batch_size * ratio / total_ratio) + t_list.append([patch_length, ratio, temp_len]) + total_length += temp_len + + t_list = sorted(t_list, key=lambda x: x[2]) + + if total_length < batch_size: + t_list[0][2] = t_list[0][2] + (batch_size - total_length) + elif total_length > batch_size: + t_list[-1][2] = t_list[-1][2] + (total_length - batch_size) + + batch1 = 0 + for patch_len, _, temp_len in t_list: + batch2 = batch1 + temp_len + mask[batch1:batch2, :, -patch_len:] = 1 + batch1 = batch2 + + perm = torch.randperm(mask.shape[0]) + mask = mask[perm] + + mask = mask.unsqueeze(-1).repeat(1, 1, 1, num_features) # mask: [bs x num_channels x num_patch x patch_len] + if unmasked_channel_indices is not None: + mask[:, unmasked_channel_indices, :, :] = 0 + + inputs_mask = inputs.masked_fill(mask.bool(), mask_value) + return inputs_mask, mask[..., 0] + + +# Copied from transformers.models.patchtst.modeling_patchtst.PatchTSTPatchify with PatchTST->PatchTSMixer +class PatchTSMixerPatchify(nn.Module): + """ + A class to patchify the time series sequence into different patches + + Returns: + `torch.Tensor` of shape `(batch_size, num_channels, num_patches, patch_length)` + """ + + def __init__(self, config: PatchTSMixerConfig): + super().__init__() + + self.sequence_length = config.context_length + self.patch_length = config.patch_length + self.patch_stride = config.patch_stride + + if self.sequence_length <= self.patch_length: + raise ValueError( + f"Sequence length ({self.sequence_length}) has to be greater than the patch length ({self.patch_length})" + ) + + # get the number of patches + self.num_patches = (max(self.sequence_length, self.patch_length) - self.patch_length) // self.patch_stride + 1 + new_sequence_length = self.patch_length + self.patch_stride * (self.num_patches - 1) + self.sequence_start = self.sequence_length - new_sequence_length + + def forward(self, past_values: torch.Tensor): + """ + Parameters: + past_values (`torch.Tensor` of shape `(batch_size, sequence_length, num_channels)`, *required*): + Input for patchification + + Returns: + `torch.Tensor` of shape `(batch_size, num_channels, num_patches, patch_length)` + """ + sequence_length = past_values.shape[-2] + if sequence_length != self.sequence_length: + raise ValueError( + f"Input sequence length ({sequence_length}) doesn't match model configuration ({self.sequence_length})." + ) + # output: [bs x new_sequence_length x num_channels] + output = past_values[:, self.sequence_start :, :] + # output: [bs x num_patches x num_input_channels x patch_length] + output = output.unfold(dimension=-2, size=self.patch_length, step=self.patch_stride) + # output: [bs x num_input_channels x num_patches x patch_length] + output = output.transpose(-2, -3).contiguous() + return output + + +# Copied from transformers.models.patchtst.modeling_patchtst.PatchTSTMasking with PatchTST->PatchTSMixer +class PatchTSMixerMasking(nn.Module): + """ + Class to perform random or forecast masking. + + Parameters: + config (`PatchTSMixerConfig`): model config + Returns: + x_mask (`torch.Tensor` of shape `(batch_size, num_channels, num_patches, patch_length)`) + Masked patched input + mask (`torch.Tensor` of shape `(batch_size, num_channels, num_patches)`) + Bool tensor indicating True on masked points + """ + + def __init__(self, config: PatchTSMixerConfig): + super().__init__() + self.random_mask_ratio = config.random_mask_ratio + self.channel_consistent_masking = config.channel_consistent_masking + self.mask_type = config.mask_type + self.num_forecast_mask_patches = config.num_forecast_mask_patches + self.unmasked_channel_indices = config.unmasked_channel_indices + self.mask_value = config.mask_value + if self.unmasked_channel_indices is not None: + self.unmasked_channel_indices = sorted(self.unmasked_channel_indices) + + def forward(self, patch_input: torch.Tensor): + """ + Parameters: + patch_input (`torch.Tensor` of shape `(batch_size, num_channels, num_patches, patch_length)`, *required*): + Patch input + + Return: + masked_input (`torch.Tensor` of shape `(batch_size, num_channels, num_patches, patch_length)`) + Masked patched input + mask (`torch.Tensor` of shape `(batch_size, num_channels, num_patches)`) + Bool tensor indicating True on masked points + + """ + if self.mask_type == "random": + masked_input, mask = random_masking( + inputs=patch_input, + mask_ratio=self.random_mask_ratio, + unmasked_channel_indices=self.unmasked_channel_indices, + channel_consistent_masking=self.channel_consistent_masking, + mask_value=self.mask_value, + ) + elif self.mask_type == "forecast": + masked_input, mask = forecast_masking( + inputs=patch_input, + num_forecast_mask_patches=self.num_forecast_mask_patches, + unmasked_channel_indices=self.unmasked_channel_indices, + mask_value=self.mask_value, + ) + else: + raise ValueError(f"Invalid mask type {self.mask_type}.") + + # mask: [bs x num_input_channels x num_patch] + mask = mask.bool() + return masked_input, mask + + +# Copied from transformers.models.patchtst.modeling_patchtst.PatchTSTStdScaler with PatchTST->PatchTSMixer +class PatchTSMixerStdScaler(nn.Module): + """ + Standardize features by calculating the mean and scaling along the first dimension, and then normalizes it by + subtracting from the mean and dividing by the standard deviation. + """ + + def __init__(self, config: PatchTSMixerConfig): + super().__init__() + self.dim = config.scaling_dim if hasattr(config, "scaling_dim") else 1 + self.keepdim = config.keepdim if hasattr(config, "keepdim") else True + self.minimum_scale = config.minimum_scale if hasattr(config, "minimum_scale") else 1e-5 + + def forward( + self, data: torch.Tensor, observed_indicator: torch.Tensor + ) -> tuple[torch.Tensor, torch.Tensor, torch.Tensor]: + """ + Parameters: + data (`torch.Tensor` of shape `(batch_size, sequence_length, num_input_channels)`): + input for Batch norm calculation + observed_indicator (`torch.BoolTensor` of shape `(batch_size, sequence_length, num_input_channels)`): + Calculating the scale on the observed indicator. + Returns: + tuple of `torch.Tensor` of shapes + (`(batch_size, sequence_length, num_input_channels)`,`(batch_size, 1, num_input_channels)`, + `(batch_size, 1, num_input_channels)`) + """ + denominator = observed_indicator.sum(self.dim, keepdim=self.keepdim) + denominator = denominator.clamp_min(1.0) + loc = (data * observed_indicator).sum(self.dim, keepdim=self.keepdim) / denominator + + variance = (((data - loc) * observed_indicator) ** 2).sum(self.dim, keepdim=self.keepdim) / denominator + scale = torch.sqrt(variance + self.minimum_scale) + return (data - loc) / scale, loc, scale + + +# Copied from transformers.models.patchtst.modeling_patchtst.PatchTSTMeanScaler with PatchTST->PatchTSMixer +class PatchTSMixerMeanScaler(nn.Module): + """ + Computes a scaling factor as the weighted average absolute value along the first dimension, and scales the data + accordingly. + """ + + def __init__(self, config: PatchTSMixerConfig): + super().__init__() + self.dim = config.scaling_dim if hasattr(config, "scaling_dim") else 1 + self.keepdim = config.keepdim if hasattr(config, "keepdim") else True + self.minimum_scale = config.minimum_scale if hasattr(config, "minimum_scale") else 1e-10 + self.default_scale = config.default_scale if hasattr(config, "default_scale") else None + + def forward( + self, data: torch.Tensor, observed_indicator: torch.Tensor + ) -> tuple[torch.Tensor, torch.Tensor, torch.Tensor]: + """ + Parameters: + data (`torch.Tensor` of shape `(batch_size, sequence_length, num_input_channels)`): + input for Batch norm calculation + observed_indicator (`torch.BoolTensor` of shape `(batch_size, sequence_length, num_input_channels)`): + Calculating the scale on the observed indicator. + Returns: + tuple of `torch.Tensor` of shapes + (`(batch_size, sequence_length, num_input_channels)`,`(batch_size, 1, num_input_channels)`, + `(batch_size, 1, num_input_channels)`) + """ + ts_sum = (data * observed_indicator).abs().sum(self.dim, keepdim=True) + num_observed = observed_indicator.sum(self.dim, keepdim=True) + + scale = ts_sum / torch.clamp(num_observed, min=1) + + # If `default_scale` is provided, we use it, otherwise we use the scale + # of the batch. + if self.default_scale is None: + batch_sum = ts_sum.sum(dim=0) + batch_observations = torch.clamp(num_observed.sum(0), min=1) + default_scale = torch.squeeze(batch_sum / batch_observations) + else: + default_scale = self.default_scale * torch.ones_like(scale) + + # apply default scale where there are no observations + scale = torch.where(num_observed > 0, scale, default_scale) + + # ensure the scale is at least `self.minimum_scale` + scale = torch.clamp(scale, min=self.minimum_scale) + scaled_data = data / scale + + if not self.keepdim: + scale = scale.squeeze(dim=self.dim) + + return scaled_data, torch.zeros_like(scale), scale + + +# Copied from transformers.models.patchtst.modeling_patchtst.PatchTSTNOPScaler with PatchTST->PatchTSMixer +class PatchTSMixerNOPScaler(nn.Module): + """ + Assigns a scaling factor equal to 1 along the first dimension, and therefore applies no scaling to the input data. + """ + + def __init__(self, config: PatchTSMixerConfig): + super().__init__() + self.dim = config.scaling_dim if hasattr(config, "scaling_dim") else 1 + self.keepdim = config.keepdim if hasattr(config, "keepdim") else True + + def forward( + self, data: torch.Tensor, observed_indicator: torch.Tensor | None = None + ) -> tuple[torch.Tensor, torch.Tensor, torch.Tensor]: + """ + Parameters: + data (`torch.Tensor` of shape `(batch_size, sequence_length, num_input_channels)`): + input for Batch norm calculation + Returns: + tuple of `torch.Tensor` of shapes + (`(batch_size, sequence_length, num_input_channels)`,`(batch_size, 1, num_input_channels)`, + `(batch_size, 1, num_input_channels)`) + """ + scale = torch.ones_like(data, requires_grad=False).mean(dim=self.dim, keepdim=self.keepdim) + loc = torch.zeros_like(data, requires_grad=False).mean(dim=self.dim, keepdim=self.keepdim) + return data, loc, scale + + +@dataclass +@auto_docstring( + custom_intro=""" + Base class for `PatchTSMixerEncoderOutput`, with potential hidden states. + """ +) +class PatchTSMixerEncoderOutput(ModelOutput): + r""" + last_hidden_state (`torch.FloatTensor` of shape `(batch_size, num_channels, num_patches, d_model)`): + Hidden-state at the output of the last layer of the model. + hidden_states (`tuple(torch.FloatTensor)`, *optional*): + Hidden-states of the model at the output of each layer. + """ + + last_hidden_state: torch.FloatTensor | None = None + hidden_states: tuple[torch.FloatTensor] | None = None + + +class PatchTSMixerEncoder(PatchTSMixerPreTrainedModel): + """ + Encoder for PatchTSMixer which inputs patched time-series and outputs patched embeddings. + + Args: + config (`PatchTSMixerConfig`): + Configuration. + """ + + def __init__(self, config: PatchTSMixerConfig): + super().__init__(config) + + self.use_return_dict = config.use_return_dict + + self.patcher = nn.Linear(config.patch_length, config.d_model) + if config.use_positional_encoding: + self.positional_encoder = PatchTSMixerPositionalEncoding(config=config) + else: + self.positional_encoder = None + self.mlp_mixer_encoder = PatchTSMixerBlock(config=config) + + # Initialize weights and apply final processing + self.post_init() + + @auto_docstring + def forward( + self, + past_values: torch.Tensor, + output_hidden_states: bool | None = False, + return_dict: bool | None = None, + **kwargs, + ) -> tuple | PatchTSMixerEncoderOutput: + r""" + past_values (`torch.FloatTensor` of shape `(batch_size, seq_length, num_input_channels)`): + Context values of the time series. For a pretraining task, this denotes the input time series to + predict the masked portion. For a forecasting task, this denotes the history/past time series values. + Similarly, for classification or regression tasks, it denotes the appropriate context values of the + time series. + + For univariate time series, `num_input_channels` dimension should be 1. For multivariate time series, + it is greater than 1. + + Returns: + `torch.FloatTensor` of shape `(batch_size, n_vars, num_patches, d_model)` + """ + + return_dict = return_dict if return_dict is not None else self.use_return_dict + + # flatten [bs x num_patch x d_model]. common_channel/mix_channel: [bs x n_vars x num_patch x d_model] + patches = self.patcher(past_values) + + # add positional encoder + if self.positional_encoder is not None: + patches = self.positional_encoder(patches) + + last_hidden_state, hidden_states = self.mlp_mixer_encoder(patches, output_hidden_states=output_hidden_states) + + if not return_dict: + return tuple( + v + for v in [ + last_hidden_state, + hidden_states, + ] + ) + + return PatchTSMixerEncoderOutput(last_hidden_state=last_hidden_state, hidden_states=hidden_states) + + +@dataclass +@auto_docstring( + custom_intro=""" + Base class for model's outputs, with potential hidden states. + """ +) +class PatchTSMixerModelOutput(ModelOutput): + r""" + last_hidden_state (`torch.FloatTensor` of shape `(batch_size, num_channels, num_patches, d_model)`): + Hidden-state at the output of the last layer of the model. + hidden_states (`tuple(torch.FloatTensor)`, *optional*): + Hidden-states of the model at the output of each layer. + patch_input (`torch.FloatTensor` of shape `(batch_size, num_channels, num_patches, patch_length)`): + Patched input data to the model. + mask (`torch.FloatTensor` of shape `(batch_size, num_channels, num_patches)`, *optional*): + Bool Tensor indicating True in masked patches and False otherwise. + loc (`torch.FloatTensor` of shape `(batch_size, 1, num_channels)`, *optional*): + Gives the mean of the context window per channel. Used for revin denorm outside the model, if revin + enabled. + scale (`torch.FloatTensor` of shape `(batch_size, 1, num_channels)`, *optional*): + Gives the std dev of the context window per channel. Used for revin denorm outside the model, if revin + enabled. + """ + + last_hidden_state: torch.FloatTensor | None = None + hidden_states: tuple[torch.FloatTensor] | None = None + patch_input: torch.FloatTensor | None = None + mask: torch.FloatTensor | None = None + loc: torch.FloatTensor | None = None + scale: torch.FloatTensor | None = None + + +@auto_docstring( + custom_intro=""" + The PatchTSMixer Model for time-series forecasting. + """ +) +class PatchTSMixerModel(PatchTSMixerPreTrainedModel): + def __init__(self, config: PatchTSMixerConfig, mask_input: bool = False): + r""" + mask_input (bool, *optional*, defaults to `False`): + Whether to mask the input using the [`PatchTSMixerMasking`] module. + """ + super().__init__(config) + + self.use_return_dict = config.use_return_dict + self.encoder = PatchTSMixerEncoder(config) + self.patching = PatchTSMixerPatchify(config) + + if mask_input is True: + self.masking = PatchTSMixerMasking(config) + else: + self.masking = None + + if config.scaling == "mean": + self.scaler = PatchTSMixerMeanScaler(config) + elif config.scaling == "std" or config.scaling is True: + self.scaler = PatchTSMixerStdScaler(config) + else: + self.scaler = PatchTSMixerNOPScaler(config) + + # Initialize weights and apply final processing + self.post_init() + + @auto_docstring + def forward( + self, + past_values: torch.Tensor, + observed_mask: torch.Tensor | None = None, + output_hidden_states: bool | None = False, + return_dict: bool | None = None, + **kwargs, + ) -> PatchTSMixerModelOutput: + r""" + past_values (`torch.FloatTensor` of shape `(batch_size, seq_length, num_input_channels)`): + Context values of the time series. For a pretraining task, this denotes the input time series to predict + the masked portion. For a forecasting task, this denotes the history/past time series values. Similarly, + for classification or regression tasks, it denotes the appropriate context values of the time series. + + For univariate time series, `num_input_channels` dimension should be 1. For multivariate time series, it is + greater than 1. + observed_mask (`torch.FloatTensor` of shape `(batch_size, sequence_length, num_input_channels)`, *optional*): + Boolean mask to indicate which `past_values` were observed and which were missing. Mask values selected + in `[0, 1]`: + - 1 for values that are **observed**, + - 0 for values that are **missing** (i.e. NaNs that were replaced by zeros). + """ + return_dict = return_dict if return_dict is not None else self.use_return_dict + + mask = None + if observed_mask is None: + observed_mask = torch.ones_like(past_values) + scaled_past_values, loc, scale = self.scaler(past_values, observed_mask) + + patched_x = self.patching(scaled_past_values) # [batch_size x num_input_channels x num_patch x patch_length + + enc_input = patched_x + if self.masking is not None: + enc_input, mask = self.masking(patched_x) + # enc_input: [batch_size x num_input_channels x num_patch x patch_length] + # mask: [batch_size x num_input_channels x num_patch] + + encoder_output = self.encoder( + enc_input, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + + if isinstance(encoder_output, tuple): + encoder_output = PatchTSMixerEncoderOutput(*encoder_output) + + if not return_dict: + return tuple( + v + for v in [ + encoder_output.last_hidden_state, + encoder_output.hidden_states, + patched_x, + mask, + loc, + scale, + ] + ) + + return PatchTSMixerModelOutput( + last_hidden_state=encoder_output.last_hidden_state, + hidden_states=encoder_output.hidden_states, + patch_input=patched_x, + mask=mask, + loc=loc, + scale=scale, + ) + + +@dataclass +@auto_docstring( + custom_intro=""" + Output type of [`PatchTSMixerForPreTrainingOutput`]. + """ +) +class PatchTSMixerForPreTrainingOutput(ModelOutput): + r""" + loss (*optional*, returned when `y` is provided, `torch.FloatTensor` of shape `()`): + Total loss + prediction_outputs (`torch.FloatTensor` of shape `(batch_size, num_input_channels, num_patches, patch_length)`): + Prediction output from the pretrain head. + last_hidden_state (`torch.FloatTensor` of shape `(batch_size, num_input_channels, num_patches, d_model)`): + Backbone embeddings before passing through the head. + hidden_states (`tuple(torch.FloatTensor)`, *optional*): + Hidden-states of the model at the output of each layer. + """ + + loss: torch.FloatTensor | None = None + prediction_outputs: torch.FloatTensor | None = None + last_hidden_state: torch.FloatTensor | None = None + hidden_states: tuple[torch.FloatTensor] | None = None + + +@auto_docstring( + custom_intro=""" + `PatchTSMixer` for mask pretraining. + """ +) +class PatchTSMixerForPretraining(PatchTSMixerPreTrainedModel): + def __init__(self, config: PatchTSMixerConfig): + super().__init__(config) + self.model = PatchTSMixerModel(config, mask_input=True) + self.head = PatchTSMixerPretrainHead(config=config) + self.masked_loss = config.masked_loss + self.use_return_dict = config.use_return_dict + + # Initialize weights and apply final processing + self.post_init() + + @auto_docstring + def forward( + self, + past_values: torch.Tensor, + observed_mask: torch.Tensor | None = None, + output_hidden_states: bool | None = False, + return_loss: bool = True, + return_dict: bool | None = None, + **kwargs, + ) -> PatchTSMixerForPreTrainingOutput: + r""" + past_values (`torch.FloatTensor` of shape `(batch_size, seq_length, num_input_channels)`): + Context values of the time series. For a pretraining task, this denotes the input time series to predict + the masked portion. For a forecasting task, this denotes the history/past time series values. Similarly, + for classification or regression tasks, it denotes the appropriate context values of the time series. + + For univariate time series, `num_input_channels` dimension should be 1. For multivariate time series, it is + greater than 1. + observed_mask (`torch.FloatTensor` of shape `(batch_size, sequence_length, num_input_channels)`, *optional*): + Boolean mask to indicate which `past_values` were observed and which were missing. Mask values selected + in `[0, 1]`: + - 1 for values that are **observed**, + - 0 for values that are **missing** (i.e. NaNs that were replaced by zeros). + return_loss (`bool`, *optional*): + Whether to return the loss in the `forward` call. + """ + return_dict = return_dict if return_dict is not None else self.use_return_dict + + if self.masked_loss is True: + loss = torch.nn.MSELoss(reduction="none") + else: + loss = torch.nn.MSELoss(reduction="mean") + + # past_values: tensor [batch_size x context_length x num_input_channels] + model_output = self.model( + past_values, + observed_mask=observed_mask, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) # x.last_hidden_state: [batch_size x nvars x num_patch x d_model] + if isinstance(model_output, tuple): + model_output = PatchTSMixerModelOutput(*model_output) + + x_hat = self.head(model_output.last_hidden_state) # tensor [batch_size x nvars x num_patch x patch_length] + + if return_loss is True: + loss_val = loss(x_hat, model_output.patch_input) + else: + loss_val = None + + # calculate masked_loss + if self.masked_loss is True and loss_val is not None: + loss_val = (loss_val.mean(dim=-1) * model_output.mask).sum() / (model_output.mask.sum() + 1e-10) + + if not return_dict: + return tuple( + v + for v in [ + loss_val, + x_hat, + model_output.last_hidden_state, + model_output.hidden_states, + ] + ) + + return PatchTSMixerForPreTrainingOutput( + loss=loss_val, + prediction_outputs=x_hat, # tensor [batch_size x nvars x num_patch x patch_length] + last_hidden_state=model_output.last_hidden_state, # x: [batch_size x nvars x num_patch x d_model] + hidden_states=model_output.hidden_states, + ) + + +@dataclass +@auto_docstring( + custom_intro=""" + Output type of [`PatchTSMixerForPredictionOutput`]. + """ +) +class PatchTSMixerForPredictionOutput(ModelOutput): + r""" + loss (*optional*, returned when `y` is provided, `torch.FloatTensor` of shape `()`): + Total loss. + prediction_outputs (`torch.FloatTensor` of shape `(batch_size, prediction_length, num_input_channels)`): + Prediction output from the forecast head. + last_hidden_state (`torch.FloatTensor` of shape `(batch_size, num_input_channels, num_patches, d_model)`): + Backbone embeddings before passing through the head. + hidden_states (`tuple(torch.FloatTensor)`, *optional*): + Hidden-states of the model at the output of each layer plus the optional initial embedding outputs. + loc (`torch.FloatTensor`, *optional* of shape `(batch_size, 1, num_input_channels)`): + Input mean + scale (`torch.FloatTensor`, *optional* of shape `(batch_size, 1, num_input_channels)`): + Input std dev + """ + + loss: torch.FloatTensor | None = None + prediction_outputs: torch.FloatTensor | None = None + last_hidden_state: torch.FloatTensor | None = None + hidden_states: tuple[torch.FloatTensor] | None = None + loc: torch.FloatTensor | None = None + scale: torch.FloatTensor | None = None + + +@dataclass +@auto_docstring( + custom_intro=""" + Base class for time series model's predictions outputs that contains the sampled values from the chosen + distribution. + """ +) +class SamplePatchTSMixerPredictionOutput(ModelOutput): + r""" + sequences (`torch.FloatTensor` of shape `(batch_size, num_samples, prediction_length, number_channels)`): + Sampled values from the chosen distribution. + """ + + sequences: torch.FloatTensor | None = None + + +@dataclass +@auto_docstring( + custom_intro=""" + Base class for time series model's predictions outputs that contains the sampled values from the chosen + distribution. + """ +) +class SamplePatchTSMixerRegressionOutput(ModelOutput): + r""" + sequences (`torch.FloatTensor` of shape `(batch_size, num_samples, prediction_length, number_channels)`): + Sampled values from the chosen distribution. + """ + + sequences: torch.FloatTensor | None = None + + +# Copied from transformers.models.time_series_transformer.modeling_time_series_transformer.nll +def nll(input: torch.distributions.Distribution, target: torch.Tensor) -> torch.Tensor: + """ + Computes the negative log likelihood loss from input distribution with respect to target. + """ + return -input.log_prob(target) + + +# Copied from transformers.models.time_series_transformer.modeling_time_series_transformer.weighted_average +def weighted_average(input_tensor: torch.Tensor, weights: torch.Tensor | None = None, dim=None) -> torch.Tensor: + """ + Computes the weighted average of a given tensor across a given `dim`, masking values associated with weight zero, + meaning instead of `nan * 0 = nan` you will get `0 * 0 = 0`. + + Args: + input_tensor (`torch.FloatTensor`): + Input tensor, of which the average must be computed. + weights (`torch.FloatTensor`, *optional*): + Weights tensor, of the same shape as `input_tensor`. + dim (`int`, *optional*): + The dim along which to average `input_tensor`. + + Returns: + `torch.FloatTensor`: The tensor with values averaged along the specified `dim`. + """ + if weights is not None: + weighted_tensor = torch.where(weights != 0, input_tensor * weights, torch.zeros_like(input_tensor)) + sum_weights = torch.clamp(weights.sum(dim=dim) if dim else weights.sum(), min=1.0) + return (weighted_tensor.sum(dim=dim) if dim else weighted_tensor.sum()) / sum_weights + else: + return input_tensor.mean(dim=dim) + + +class PatchTSMixerForPrediction(PatchTSMixerPreTrainedModel): + r""" + `PatchTSMixer` for forecasting application. + + Args: + config (`PatchTSMixerConfig`): + Configuration. + + Returns: + `None`. + """ + + def __init__(self, config: PatchTSMixerConfig): + super().__init__(config) + self.loss = config.loss + self.use_return_dict = config.use_return_dict + self.prediction_channel_indices = config.prediction_channel_indices + self.num_parallel_samples = config.num_parallel_samples + + if config.loss == "mse": + self.distribution_output = None + else: + dim = config.prediction_length + distribution_output_map = { + "student_t": StudentTOutput, + "normal": NormalOutput, + "negative_binomial": NegativeBinomialOutput, + } + output_class = distribution_output_map.get(config.distribution_output) + if output_class is not None: + self.distribution_output = output_class(dim=dim) + else: + raise ValueError(f"Unknown distribution output {config.distribution_output}") + + self.model = PatchTSMixerModel(config) + self.head = PatchTSMixerForPredictionHead( + config=config, + distribution_output=self.distribution_output, + ) + + # Initialize weights and apply final processing + self.post_init() + + @auto_docstring + def forward( + self, + past_values: torch.Tensor, + observed_mask: torch.Tensor | None = None, + future_values: torch.Tensor | None = None, + output_hidden_states: bool | None = False, + return_loss: bool = True, + return_dict: bool | None = None, + **kwargs, + ) -> PatchTSMixerForPredictionOutput: + r""" + past_values (`torch.FloatTensor` of shape `(batch_size, seq_length, num_input_channels)`): + Context values of the time series. For a pretraining task, this denotes the input time series to predict + the masked portion. For a forecasting task, this denotes the history/past time series values. Similarly, + for classification or regression tasks, it denotes the appropriate context values of the time series. + + For univariate time series, `num_input_channels` dimension should be 1. For multivariate time series, it is + greater than 1. + observed_mask (`torch.FloatTensor` of shape `(batch_size, sequence_length, num_input_channels)`, *optional*): + Boolean mask to indicate which `past_values` were observed and which were missing. Mask values selected + in `[0, 1]`: + - 1 for values that are **observed**, + - 0 for values that are **missing** (i.e. NaNs that were replaced by zeros). + future_values (`torch.FloatTensor` of shape `(batch_size, target_len, num_input_channels)` for forecasting,: + `(batch_size, num_targets)` for regression, or `(batch_size,)` for classification, *optional*): + Target values of the time series, that serve as labels for the model. The `future_values` is what the + Transformer needs during training to learn to output, given the `past_values`. Note that, this is NOT + required for a pretraining task. + + For a forecasting task, the shape is be `(batch_size, target_len, num_input_channels)`. Even if we want + to forecast only specific channels by setting the indices in `prediction_channel_indices` parameter, + pass the target data with all channels, as channel Filtering for both prediction and target will be + manually applied before the loss computation. + return_loss (`bool`, *optional*): + Whether to return the loss in the `forward` call. + """ + if self.loss == "mse": + loss = nn.MSELoss(reduction="mean") + elif self.loss == "nll": + loss = nll + else: + raise ValueError("Invalid loss function: Allowed values: mse and nll") + + return_dict = return_dict if return_dict is not None else self.use_return_dict + + # past_values: tensor [batch_size x context_length x num_input_channels] + model_output = self.model( + past_values, + observed_mask=observed_mask, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) # model_output: [batch_size x nvars x num_patch x d_model] + if isinstance(model_output, tuple): + model_output = PatchTSMixerModelOutput(*model_output) + + # tensor [batch_size x prediction_length x num_input_channels] + y_hat = self.head(model_output.last_hidden_state) + + loss_val = None + if self.prediction_channel_indices is not None: + if self.distribution_output: + distribution = self.distribution_output.distribution( + y_hat, + loc=model_output.loc[..., self.prediction_channel_indices], + scale=model_output.scale[..., self.prediction_channel_indices], + ) + if future_values is not None and return_loss is True: + loss_val = loss( + distribution, + future_values[..., self.prediction_channel_indices], + ) + # take average of the loss + loss_val = weighted_average(loss_val) + else: + y_hat = ( + y_hat * model_output.scale[..., self.prediction_channel_indices] + + model_output.loc[..., self.prediction_channel_indices] + ) + if future_values is not None and return_loss is True: + loss_val = loss(y_hat, future_values[..., self.prediction_channel_indices]) + else: + if self.distribution_output: + distribution = self.distribution_output.distribution( + y_hat, loc=model_output.loc, scale=model_output.scale + ) + if future_values is not None and return_loss is True: + loss_val = loss(distribution, future_values) + loss_val = weighted_average(loss_val) + else: + y_hat = y_hat * model_output.scale + model_output.loc + if future_values is not None and return_loss is True: + loss_val = loss(y_hat, future_values) + + if self.prediction_channel_indices is not None: + loc = model_output.loc[..., self.prediction_channel_indices] + scale = model_output.scale[..., self.prediction_channel_indices] + else: + loc = model_output.loc + scale = model_output.scale + + if not return_dict: + return tuple( + v + for v in [ + loss_val, + y_hat, + model_output.last_hidden_state, + model_output.hidden_states, + loc, + scale, + ] + ) + + return PatchTSMixerForPredictionOutput( + loss=loss_val, + prediction_outputs=y_hat, # tensor [batch_size x prediction_length x num_input_channels] + last_hidden_state=model_output.last_hidden_state, # x: [batch_size x nvars x num_patch x d_model] + hidden_states=model_output.hidden_states, + loc=loc, + scale=scale, + ) + + @torch.no_grad() + def generate( + self, + past_values: torch.Tensor, + observed_mask: torch.Tensor | None = None, + ) -> SamplePatchTSMixerPredictionOutput: + """ + Generate sequences of sample predictions from a model with a probability distribution head. + + Args: + past_values (`torch.FloatTensor` of shape `(batch_size, sequence_length, num_input_channels)`): + Past values of the time series that serves as context in order to predict the future. + + observed_mask (`torch.BoolTensor` of shape `(batch_size, sequence_length, num_input_channels)`, *optional*): + Boolean mask to indicate which `past_values` were observed and which were missing. Mask values selected + in `[0, 1]`: + + - 1 for values that are **observed**, + - 0 for values that are **missing** (i.e. NaNs that were replaced by zeros). + + Return: + [`SamplePatchTSMixerPredictionOutput`] where the outputs `sequences` tensor will have shape `(batch_size, + number of samples, prediction_length, num_input_channels)`. + """ + # get number of samples + num_parallel_samples = self.num_parallel_samples + + # get model output + outputs = self( + past_values=past_values, + future_values=None, + observed_mask=observed_mask, + output_hidden_states=False, + ) + + # get distribution + + distribution = self.distribution_output.distribution( + outputs.prediction_outputs, loc=outputs.loc, scale=outputs.scale + ) + + # get samples: list of [batch_size x prediction_length x num_channels] + samples = [distribution.sample() for _ in range(num_parallel_samples)] + + # stack tensors + samples = torch.stack(samples, dim=1) # [batch_size x num_samples x prediction_length x num_channels] + return SamplePatchTSMixerPredictionOutput(sequences=samples) + + +@dataclass +@auto_docstring( + custom_intro=""" + Output type of [`PatchTSMixerForTimeSeriesClassificationOutput`]. + """ +) +class PatchTSMixerForTimeSeriesClassificationOutput(ModelOutput): + r""" + loss (*optional*, returned when `y` is provided, `torch.FloatTensor` of shape `()`): + Total loss. + prediction_outputs (`torch.FloatTensor` of shape `(batch_size, num_labels)`): + Prediction output from the classification head. + last_hidden_state (`torch.FloatTensor` of shape `(batch_size, num_input_channels, num_patches, d_model)`): + Backbone embeddings before passing through the head. + hidden_states (`tuple(torch.FloatTensor)`, *optional*): + Hidden-states of the model at the output of each layer plus the optional initial embedding outputs. + """ + + loss: torch.FloatTensor | None = None + prediction_outputs: torch.FloatTensor | None = None + last_hidden_state: torch.FloatTensor | None = None + hidden_states: tuple[torch.FloatTensor] | None = None + + +class PatchTSMixerForTimeSeriesClassification(PatchTSMixerPreTrainedModel): + r""" + `PatchTSMixer` for classification application. + + Args: + config (`PatchTSMixerConfig`): + Configuration. + + Returns: + `None`. + """ + + def __init__(self, config: PatchTSMixerConfig): + super().__init__(config) + + self.model = PatchTSMixerModel(config) + self.head = PatchTSMixerLinearHead( + config=config, + ) + self.use_return_dict = config.use_return_dict + if config.scaling in ["std", "mean", True]: + self.inject_scale = InjectScalerStatistics4D(d_model=config.d_model, num_patches=config.num_patches) + else: + self.inject_scale = None + + # Initialize weights and apply final processing + self.post_init() + + @auto_docstring + def forward( + self, + past_values: torch.Tensor, + target_values: torch.Tensor | None = None, + output_hidden_states: bool | None = False, + return_loss: bool = True, + return_dict: bool | None = None, + **kwargs, + ) -> PatchTSMixerForTimeSeriesClassificationOutput: + r""" + past_values (`torch.FloatTensor` of shape `(batch_size, seq_length, num_input_channels)`): + Context values of the time series. For a pretraining task, this denotes the input time series to predict + the masked portion. For a forecasting task, this denotes the history/past time series values. Similarly, + for classification or regression tasks, it denotes the appropriate context values of the time series. + + For univariate time series, `num_input_channels` dimension should be 1. For multivariate time series, it is + greater than 1. + target_values (`torch.FloatTensor` of shape `(batch_size, target_len, num_input_channels)` for forecasting, + `(batch_size, num_targets)` for regression, or `(batch_size,)` for classification, *optional*): + Target + values of the time series, that serve as labels for the model. The `target_values` is what the + Transformer needs during training to learn to output, given the `past_values`. Note that, this is NOT + required for a pretraining task. + + For a forecasting task, the shape is be `(batch_size, target_len, num_input_channels)`. Even if we want + to forecast only specific channels by setting the indices in `prediction_channel_indices` parameter, + pass the target data with all channels, as channel Filtering for both prediction and target will be + manually applied before the loss computation. + + For a classification task, it has a shape of `(batch_size,)`. + + For a regression task, it has a shape of `(batch_size, num_targets)`. + return_loss (`bool`, *optional*): + Whether to return the loss in the `forward` call. + """ + + loss = torch.nn.CrossEntropyLoss() + + return_dict = return_dict if return_dict is not None else self.use_return_dict + + model_output = self.model( + past_values, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) # x: [batch_size x nvars x num_patch x d_model] + if isinstance(model_output, tuple): + model_output = PatchTSMixerModelOutput(*model_output) + + if self.inject_scale is not None: + model_output.last_hidden_state = self.inject_scale( + model_output.last_hidden_state, + loc=model_output.loc, + scale=model_output.scale, + ) # x: [batch_size x nvars x num_patch x d_model] + + y_hat = self.head(model_output.last_hidden_state) # tensor [batch_size x n_labels] + + if target_values is not None and return_loss is True: + loss_val = loss(y_hat, target_values) + else: + loss_val = None + + if not return_dict: + return tuple( + v + for v in [ + loss_val, + y_hat, + model_output.last_hidden_state, + model_output.hidden_states, + ] + ) + + return PatchTSMixerForTimeSeriesClassificationOutput( + loss=loss_val, + prediction_outputs=y_hat, # tensor [batch_size x n_labels] + last_hidden_state=model_output.last_hidden_state, # x: [batch_size x nvars x num_patch x d_model] + hidden_states=model_output.hidden_states, + ) + + +@dataclass +@auto_docstring( + custom_intro=""" + Output type of [`PatchTSMixerForRegressionOutput`]. + """ +) +class PatchTSMixerForRegressionOutput(ModelOutput): + r""" + loss (*optional*, returned when `y` is provided, `torch.FloatTensor` of shape `()`): + Total loss. + regression_outputs (`torch.FloatTensor` of shape `(batch_size, num_targets)`): + Prediction output from the regression head. + last_hidden_state (`torch.FloatTensor` of shape `(batch_size, num_input_channels, num_patches, d_model)`): + Backbone embeddings before passing through the head. + hidden_states (`tuple(torch.FloatTensor)`, *optional*): + Hidden-states of the model at the output of each layer plus the optional initial embedding outputs. + """ + + loss: torch.FloatTensor | None = None + regression_outputs: torch.FloatTensor | None = None + last_hidden_state: torch.FloatTensor | None = None + hidden_states: tuple[torch.FloatTensor] | None = None + + +class InjectScalerStatistics4D(nn.Module): + def __init__(self, d_model: int, num_patches: int, expansion: int = 2): + super().__init__() + + self.inverse_trans_expansion = nn.Linear(d_model + 2, expansion * d_model) + self.inverse_trans_compression = nn.Linear(expansion * d_model, d_model) + self.map_scale_expansion = nn.Linear(2, 2 * expansion) + self.map_scale_compression = nn.Linear(2 * expansion, 2) + self.num_patches = num_patches + + def forward(self, inputs: torch.Tensor, loc: torch.Tensor, scale: torch.Tensor): + """ + Args: + inputs (`torch.Tensor` of shape `(batch_size, num_input_channels, num_patch, d_model)`) + loc (`torch.Tensor` of shape `(batch_size, 1, num_input_channels)`) + scale (`torch.Tensor` of shape `(batch_size, 1, num_input_channels)`) + Returns: + `torch.Tensor` of shape `(batch_size, num_input_channels, num_patch, d_model)` + """ + + mean = loc.transpose(-1, -2) # [batch_size x n_channels x 1 ] + mean = mean.unsqueeze(-2) # [batch_size x n_channels x 1 x 1] + mean = mean.repeat(1, 1, self.num_patches, 1) # [batch_size x n_channels x num_patch x 1] + + stdev = scale.transpose(-1, -2) # [batch_size x n_channels x 1 ] + stdev = stdev.unsqueeze(-2) # [batch_size x n_channels x 1 x 1] + stdev = stdev.repeat(1, 1, self.num_patches, 1) # [batch_size x n_channels x num_patch x 1] + + concat_stats = torch.cat([mean, stdev], dim=-1) # [batch_size x n_channels x num_patch x 2] + + concat_stats = self.map_scale_expansion(concat_stats) # [batch_size x n_channels x num_patch x (2*expansion)] + concat_stats = self.map_scale_compression(concat_stats) # [batch_size x n_channels x num_patch x 2] + + inputs = torch.cat([inputs, concat_stats], dim=-1) # [batch_size x channels x num_patch x d_model+2] + inputs = self.inverse_trans_expansion(inputs) # [batch_size x channels x num_patch x (expansion*d_model)] + inputs = self.inverse_trans_compression(inputs) # [batch_size x channels x num_patch x d_model] + + return inputs + + +@auto_docstring( + custom_intro=""" + `PatchTSMixer` for regression application. + """ +) +class PatchTSMixerForRegression(PatchTSMixerPreTrainedModel): + def __init__(self, config: PatchTSMixerConfig): + super().__init__(config) + + self.model = PatchTSMixerModel(config) + + self.loss = config.loss + self.distribution_output = config.distribution_output + + self.use_return_dict = config.use_return_dict + self.num_parallel_samples = config.num_parallel_samples + + if config.loss == "mse": + self.distribution_output = None + else: + distribution_output_map = { + "student_t": StudentTOutput, + "normal": NormalOutput, + "negative_binomial": NegativeBinomialOutput, + } + output_class = distribution_output_map.get(config.distribution_output) + if output_class is not None: + self.distribution_output = output_class(dim=config.num_targets) + else: + raise ValueError(f"Unknown distribution output {config.distribution_output}") + + if config.scaling in ["std", "mean", True]: + self.inject_scale = InjectScalerStatistics4D(d_model=config.d_model, num_patches=config.num_patches) + else: + self.inject_scale = None + + self.head = PatchTSMixerLinearHead( + config=config, + distribution_output=self.distribution_output, + ) + + # Initialize weights and apply final processing + self.post_init() + + @auto_docstring + def forward( + self, + past_values: torch.Tensor, + target_values: torch.Tensor | None = None, + output_hidden_states: bool | None = False, + return_loss: bool = True, + return_dict: bool | None = None, + **kwargs, + ) -> PatchTSMixerForRegressionOutput: + r""" + past_values (`torch.FloatTensor` of shape `(batch_size, seq_length, num_input_channels)`): + Context values of the time series. For a pretraining task, this denotes the input time series to predict + the masked portion. For a forecasting task, this denotes the history/past time series values. Similarly, + for classification or regression tasks, it denotes the appropriate context values of the time series. + + For univariate time series, `num_input_channels` dimension should be 1. For multivariate time series, it is + greater than 1. + target_values (`torch.FloatTensor` of shape `(batch_size, target_len, num_input_channels)` for forecasting, + `(batch_size, num_targets)` for regression, or `(batch_size,)` for classification, *optional*): + Target values of the time series, that serve as labels for the model. The `target_values` is what the + Transformer needs during training to learn to output, given the `past_values`. Note that, this is NOT + required for a pretraining task. + + For a forecasting task, the shape is be `(batch_size, target_len, num_input_channels)`. Even if we want + to forecast only specific channels by setting the indices in `prediction_channel_indices` parameter, + pass the target data with all channels, as channel Filtering for both prediction and target will be + manually applied before the loss computation. + + For a classification task, it has a shape of `(batch_size,)`. + + For a regression task, it has a shape of `(batch_size, num_targets)`. + return_loss (`bool`, *optional*): + Whether to return the loss in the `forward` call. + """ + + if self.loss == "mse": + loss = nn.MSELoss(reduction="mean") + elif self.loss == "nll": + loss = nll + else: + raise ValueError("Invalid loss function: Allowed values: mse and nll") + + return_dict = return_dict if return_dict is not None else self.use_return_dict + model_output = self.model( + past_values, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) # model_output: [batch_size x nvars x num_patch x d_model] + if isinstance(model_output, tuple): + model_output = PatchTSMixerModelOutput(*model_output) + + if self.inject_scale is not None: + model_output.last_hidden_state = self.inject_scale( + model_output.last_hidden_state, + loc=model_output.loc, + scale=model_output.scale, + ) # x: [batch_size x nvars x num_patch x d_model] + + y_hat = self.head(model_output.last_hidden_state) # [batch_size x num_targets] + + if target_values is not None and return_loss is True: + if self.distribution_output: + if self.distribution_output == "negative_binomial" and torch.any(target_values < 0): + raise Exception("target_values cannot be negative for negative_binomial distribution.") + distribution = self.distribution_output.distribution(y_hat) + # y_hat should be a 2-tuple, each with dimension [bs, num_targets] + y_hat = tuple(item.view(-1, self.config.num_targets) for item in y_hat) + loss_val = loss(distribution, target_values) + # take average of the loss + loss_val = weighted_average(loss_val) + else: + loss_val = loss(y_hat, target_values) + else: + loss_val = None + + if not return_dict: + return tuple( + v + for v in [ + loss_val, + y_hat, + model_output.last_hidden_state, + model_output.hidden_states, + ] + ) + + return PatchTSMixerForRegressionOutput( + loss=loss_val, + regression_outputs=y_hat, # tensor [batch_size x num_targets] + last_hidden_state=model_output.last_hidden_state, # [batch_size x nvars x num_patch x d_model] + hidden_states=model_output.hidden_states, + ) + + @torch.no_grad() + def generate( + self, + past_values: torch.Tensor, + ) -> SamplePatchTSMixerRegressionOutput: + """ + Generate sequences of sample predictions from a model with a probability distribution head. + + Args: + past_values (`torch.FloatTensor` of shape `(batch_size, sequence_length, num_input_channels)`): + Past values of the time series that serves as context in order to predict the target values. + + Return: + [`SamplePatchTSMixerRegressionOutput`] where the outputs `sequences` tensor will have shape `(batch_size, + number of samples, num_targets)`. + """ + # get number of samples + num_parallel_samples = self.num_parallel_samples + + # get model output + outputs = self( + past_values=past_values, + target_values=None, + output_hidden_states=False, + ) + + # get distribution + distribution = self.distribution_output.distribution(outputs.regression_outputs) + + # get samples + samples = [ + distribution.sample() for _ in range(num_parallel_samples) + ] # samples: list of [batch_size x num_targets] + # stack tensors + # [batch_size x num_samples x num_targets] + samples = torch.stack(samples, dim=1).view(-1, num_parallel_samples, self.config.num_targets) + return SamplePatchTSMixerRegressionOutput(sequences=samples) + + +__all__ = [ + "PatchTSMixerPreTrainedModel", + "PatchTSMixerModel", + "PatchTSMixerForPretraining", + "PatchTSMixerForPrediction", + "PatchTSMixerForTimeSeriesClassification", + "PatchTSMixerForRegression", +] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/patchtst/__init__.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/patchtst/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..f1a045bfb1820424f77c9b798a3c027569eed3eb --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/patchtst/__init__.py @@ -0,0 +1,27 @@ +# Copyright 2024 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from typing import TYPE_CHECKING + +from ...utils import _LazyModule +from ...utils.import_utils import define_import_structure + + +if TYPE_CHECKING: + from .configuration_patchtst import * + from .modeling_patchtst import * +else: + import sys + + _file = globals()["__file__"] + sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__) diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/patchtst/configuration_patchtst.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/patchtst/configuration_patchtst.py new file mode 100644 index 0000000000000000000000000000000000000000..856078a87025f0da4f9a566086d7fabec2bf9bd8 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/patchtst/configuration_patchtst.py @@ -0,0 +1,253 @@ +# Copyright 2023 The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""PatchTST model configuration""" + +from transformers.configuration_utils import PreTrainedConfig +from transformers.utils import logging + + +logger = logging.get_logger(__name__) + + +class PatchTSTConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of an [`PatchTSTModel`]. It is used to instantiate an + PatchTST model according to the specified arguments, defining the model architecture. + [ibm/patchtst](https://huggingface.co/ibm/patchtst) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + num_input_channels (`int`, *optional*, defaults to 1): + The size of the target variable which by default is 1 for univariate targets. Would be > 1 in case of + multivariate targets. + context_length (`int`, *optional*, defaults to 32): + The context length of the input sequence. + distribution_output (`str`, *optional*, defaults to `"student_t"`): + The distribution emission head for the model when loss is "nll". Could be either "student_t", "normal" or + "negative_binomial". + loss (`str`, *optional*, defaults to `"mse"`): + The loss function for the model corresponding to the `distribution_output` head. For parametric + distributions it is the negative log likelihood ("nll") and for point estimates it is the mean squared + error "mse". + patch_length (`int`, *optional*, defaults to 1): + Define the patch length of the patchification process. + patch_stride (`int`, *optional*, defaults to 1): + Define the stride of the patchification process. + num_hidden_layers (`int`, *optional*, defaults to 3): + Number of hidden layers. + d_model (`int`, *optional*, defaults to 128): + Dimensionality of the transformer layers. + num_attention_heads (`int`, *optional*, defaults to 4): + Number of attention heads for each attention layer in the Transformer encoder. + share_embedding (`bool`, *optional*, defaults to `True`): + Sharing the input embedding across all channels. + channel_attention (`bool`, *optional*, defaults to `False`): + Activate channel attention block in the Transformer to allow channels to attend each other. + ffn_dim (`int`, *optional*, defaults to 512): + Dimension of the "intermediate" (often named feed-forward) layer in the Transformer encoder. + norm_type (`str` , *optional*, defaults to `"batchnorm"`): + Normalization at each Transformer layer. Can be `"batchnorm"` or `"layernorm"`. + norm_eps (`float`, *optional*, defaults to 1e-05): + A value added to the denominator for numerical stability of normalization. + attention_dropout (`float`, *optional*, defaults to 0.0): + The dropout probability for the attention probabilities. + positional_dropout (`float`, *optional*, defaults to 0.0): + The dropout probability in the positional embedding layer. + path_dropout (`float`, *optional*, defaults to 0.0): + The dropout path in the residual block. + ff_dropout (`float`, *optional*, defaults to 0.0): + The dropout probability used between the two layers of the feed-forward networks. + bias (`bool`, *optional*, defaults to `True`): + Whether to add bias in the feed-forward networks. + activation_function (`str`, *optional*, defaults to `"gelu"`): + The non-linear activation function (string) in the Transformer.`"gelu"` and `"relu"` are supported. + pre_norm (`bool`, *optional*, defaults to `True`): + Normalization is applied before self-attention if pre_norm is set to `True`. Otherwise, normalization is + applied after residual block. + positional_encoding_type (`str`, *optional*, defaults to `"sincos"`): + Positional encodings. Options `"random"` and `"sincos"` are supported. + use_cls_token (`bool`, *optional*, defaults to `False`): + Whether cls token is used. + init_std (`float`, *optional*, defaults to 0.02): + The standard deviation of the truncated normal weight initialization distribution. + share_projection (`bool`, *optional*, defaults to `True`): + Sharing the projection layer across different channels in the forecast head. + scaling (`Union`, *optional*, defaults to `"std"`): + Whether to scale the input targets via "mean" scaler, "std" scaler or no scaler if `None`. If `True`, the + scaler is set to "mean". + do_mask_input (`bool`, *optional*): + Apply masking during the pretraining. + mask_type (`str`, *optional*, defaults to `"random"`): + Masking type. Only `"random"` and `"forecast"` are currently supported. + random_mask_ratio (`float`, *optional*, defaults to 0.5): + Masking ratio applied to mask the input data during random pretraining. + num_forecast_mask_patches (`int` or `list`, *optional*, defaults to `[2]`): + Number of patches to be masked at the end of each batch sample. If it is an integer, + all the samples in the batch will have the same number of masked patches. If it is a list, + samples in the batch will be randomly masked by numbers defined in the list. This argument is only used + for forecast pretraining. + channel_consistent_masking (`bool`, *optional*, defaults to `False`): + If channel consistent masking is True, all the channels will have the same masking pattern. + unmasked_channel_indices (`list`, *optional*): + Indices of channels that are not masked during pretraining. Values in the list are number between 1 and + `num_input_channels` + mask_value (`int`, *optional*, defaults to 0): + Values in the masked patches will be filled by `mask_value`. + pooling_type (`str`, *optional*, defaults to `"mean"`): + Pooling of the embedding. `"mean"`, `"max"` and `None` are supported. + head_dropout (`float`, *optional*, defaults to 0.0): + The dropout probability for head. + prediction_length (`int`, *optional*, defaults to 24): + The prediction horizon that the model will output. + num_targets (`int`, *optional*, defaults to 1): + Number of targets for regression and classification tasks. For classification, it is the number of + classes. + output_range (`list`, *optional*): + Output range for regression task. The range of output values can be set to enforce the model to produce + values within a range. + num_parallel_samples (`int`, *optional*, defaults to 100): + The number of samples is generated in parallel for probabilistic prediction. + + + ```python + >>> from transformers import PatchTSTConfig, PatchTSTModel + + >>> # Initializing an PatchTST configuration with 12 time steps for prediction + >>> configuration = PatchTSTConfig(prediction_length=12) + + >>> # Randomly initializing a model (with random weights) from the configuration + >>> model = PatchTSTModel(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "patchtst" + attribute_map = { + "hidden_size": "d_model", + "num_attention_heads": "num_attention_heads", + "num_hidden_layers": "num_hidden_layers", + } + + def __init__( + self, + # time series specific configuration + num_input_channels: int = 1, + context_length: int = 32, + distribution_output: str = "student_t", + loss: str = "mse", + # PatchTST arguments + patch_length: int = 1, + patch_stride: int = 1, + # Transformer architecture configuration + num_hidden_layers: int = 3, + d_model: int = 128, + num_attention_heads: int = 4, + share_embedding: bool = True, + channel_attention: bool = False, + ffn_dim: int = 512, + norm_type: str = "batchnorm", + norm_eps: float = 1e-05, + attention_dropout: float = 0.0, + positional_dropout: float = 0.0, + path_dropout: float = 0.0, + ff_dropout: float = 0.0, + bias: bool = True, + activation_function: str = "gelu", + pre_norm: bool = True, + positional_encoding_type: str = "sincos", + use_cls_token: bool = False, + init_std: float = 0.02, + share_projection: bool = True, + scaling: str | bool | None = "std", + # mask pretraining + do_mask_input: bool | None = None, + mask_type: str = "random", + random_mask_ratio: float = 0.5, + num_forecast_mask_patches: list[int] | int | None = [2], + channel_consistent_masking: bool | None = False, + unmasked_channel_indices: list[int] | None = None, + mask_value: int = 0, + # head + pooling_type: str = "mean", + head_dropout: float = 0.0, + prediction_length: int = 24, + num_targets: int = 1, + output_range: list | None = None, + # distribution head + num_parallel_samples: int = 100, + **kwargs, + ): + # time series specific configuration + self.context_length = context_length + self.num_input_channels = num_input_channels # n_vars + self.loss = loss + self.distribution_output = distribution_output + self.num_parallel_samples = num_parallel_samples + + # Transformer architecture configuration + self.d_model = d_model + self.num_attention_heads = num_attention_heads + self.ffn_dim = ffn_dim + self.num_hidden_layers = num_hidden_layers + self.attention_dropout = attention_dropout + self.share_embedding = share_embedding + self.channel_attention = channel_attention + self.norm_type = norm_type + self.norm_eps = norm_eps + self.positional_dropout = positional_dropout + self.path_dropout = path_dropout + self.ff_dropout = ff_dropout + self.bias = bias + self.activation_function = activation_function + self.pre_norm = pre_norm + self.positional_encoding_type = positional_encoding_type + self.use_cls_token = use_cls_token + self.init_std = init_std + self.scaling = scaling + + # PatchTST parameters + self.patch_length = patch_length + self.patch_stride = patch_stride + + # Mask pretraining + self.do_mask_input = do_mask_input + self.mask_type = mask_type + self.random_mask_ratio = random_mask_ratio # for random masking + self.num_forecast_mask_patches = num_forecast_mask_patches # for forecast masking + self.channel_consistent_masking = channel_consistent_masking + self.unmasked_channel_indices = unmasked_channel_indices + self.mask_value = mask_value + + # general head params + self.pooling_type = pooling_type + self.head_dropout = head_dropout + + # For prediction head + self.share_projection = share_projection + self.prediction_length = prediction_length + + # For prediction and regression head + self.num_parallel_samples = num_parallel_samples + + # Regression + self.num_targets = num_targets + self.output_range = output_range + + super().__init__(**kwargs) + + +__all__ = ["PatchTSTConfig"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/patchtst/modeling_patchtst.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/patchtst/modeling_patchtst.py new file mode 100644 index 0000000000000000000000000000000000000000..973074c836334b5087d092e1719823b629dfdac3 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/patchtst/modeling_patchtst.py @@ -0,0 +1,1974 @@ +# Copyright 2023 IBM & Hugging Face. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""PyTorch PatchTST model.""" + +import math +from collections.abc import Callable +from dataclasses import dataclass + +import torch +from torch import nn + +from ... import initialization as init +from ...activations import ACT2CLS +from ...integrations.deepspeed import is_deepspeed_zero3_enabled +from ...modeling_flash_attention_utils import FlashAttentionKwargs +from ...modeling_outputs import BaseModelOutput +from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel +from ...processing_utils import Unpack +from ...time_series_utils import NegativeBinomialOutput, NormalOutput, StudentTOutput +from ...utils import ModelOutput, TransformersKwargs, auto_docstring, logging +from .configuration_patchtst import PatchTSTConfig + + +logger = logging.get_logger(__name__) + + +# Copied from transformers.models.bert.modeling_bert.eager_attention_forward +def eager_attention_forward( + module: nn.Module, + query: torch.Tensor, + key: torch.Tensor, + value: torch.Tensor, + attention_mask: torch.Tensor | None, + scaling: float | None = None, + dropout: float = 0.0, + **kwargs: Unpack[TransformersKwargs], +): + if scaling is None: + scaling = query.size(-1) ** -0.5 + + # Take the dot product between "query" and "key" to get the raw attention scores. + attn_weights = torch.matmul(query, key.transpose(2, 3)) * scaling + + if attention_mask is not None: + attn_weights = attn_weights + attention_mask + + attn_weights = nn.functional.softmax(attn_weights, dim=-1) + attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training) + + attn_output = torch.matmul(attn_weights, value) + attn_output = attn_output.transpose(1, 2).contiguous() + + return attn_output, attn_weights + + +# Copied from transformers.models.wav2vec2.modeling_wav2vec2.Wav2Vec2Attention with Wav2Vec2->PatchTST +class PatchTSTAttention(nn.Module): + """Multi-headed attention from 'Attention Is All You Need' paper""" + + def __init__( + self, + embed_dim: int, + num_heads: int, + dropout: float = 0.0, + is_decoder: bool = False, + bias: bool = True, + is_causal: bool = False, + config: PatchTSTConfig | None = None, + ): + super().__init__() + self.embed_dim = embed_dim + self.num_heads = num_heads + self.dropout = dropout + self.head_dim = embed_dim // num_heads + self.config = config + + if (self.head_dim * num_heads) != self.embed_dim: + raise ValueError( + f"embed_dim must be divisible by num_heads (got `embed_dim`: {self.embed_dim}" + f" and `num_heads`: {num_heads})." + ) + self.scaling = self.head_dim**-0.5 + self.is_decoder = is_decoder + self.is_causal = is_causal + + self.k_proj = nn.Linear(embed_dim, embed_dim, bias=bias) + self.v_proj = nn.Linear(embed_dim, embed_dim, bias=bias) + self.q_proj = nn.Linear(embed_dim, embed_dim, bias=bias) + self.out_proj = nn.Linear(embed_dim, embed_dim, bias=bias) + + def forward( + self, + hidden_states: torch.Tensor, + key_value_states: torch.Tensor | None = None, + attention_mask: torch.Tensor | None = None, + output_attentions: bool | None = False, + # TODO: we need a refactor so that the different attention modules can get their specific kwargs + # ATM, we have mixed things encoder, decoder, and encoder-decoder attn + **kwargs: Unpack[FlashAttentionKwargs], + ) -> tuple[torch.Tensor, torch.Tensor | None, tuple[torch.Tensor] | None]: + """Input shape: Batch x Time x Channel""" + + # if key_value_states are provided this layer is used as a cross-attention layer + # for the decoder + is_cross_attention = key_value_states is not None + + # determine input shapes + bsz, tgt_len = hidden_states.shape[:-1] + src_len = key_value_states.shape[1] if is_cross_attention else tgt_len + + q_input_shape = (bsz, tgt_len, -1, self.head_dim) + kv_input_shape = (bsz, src_len, -1, self.head_dim) + + # get query proj + query_states = self.q_proj(hidden_states).view(*q_input_shape).transpose(1, 2) + + current_states = key_value_states if is_cross_attention else hidden_states + key_states = self.k_proj(current_states).view(*kv_input_shape).transpose(1, 2) + value_states = self.v_proj(current_states).view(*kv_input_shape).transpose(1, 2) + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, eager_attention_forward + ) + + attn_output, attn_weights = attention_interface( + self, + query_states, + key_states, + value_states, + attention_mask, + dropout=0.0 if not self.training else self.dropout, + scaling=self.scaling, + output_attentions=output_attentions, + **kwargs, + ) + + attn_output = attn_output.reshape(bsz, tgt_len, -1).contiguous() + attn_output = self.out_proj(attn_output) + + return attn_output, attn_weights, None + + +class PatchTSTBatchNorm(nn.Module): + """ + Compute batch normalization over the sequence length (time) dimension. + """ + + def __init__(self, config: PatchTSTConfig): + super().__init__() + self.batchnorm = nn.BatchNorm1d(config.d_model, eps=config.norm_eps) + + def forward(self, inputs: torch.Tensor): + """ + Parameters: + inputs (`torch.Tensor` of shape `(batch_size, sequence_length, d_model)`): + input for Batch norm calculation + Returns: + `torch.Tensor` of shape `(batch_size, sequence_length, d_model)` + """ + output = inputs.transpose(1, 2) # output: (batch_size, d_model, sequence_length) + output = self.batchnorm(output) + return output.transpose(1, 2) + + +def random_masking( + inputs: torch.Tensor, + mask_ratio: float, + unmasked_channel_indices: list | None = None, + channel_consistent_masking: bool = False, + mask_value: int = 0, +): + """random_masking: Mask the input considering the control variables. + + Args: + inputs (`torch.Tensor` of shape `(batch_size, num_channels, sequence_length, num_features)`): + The input tensor to mask. + mask_ratio (`float`): + Masking ratio applied to mask the input data during random pretraining. It is the number between 0 and 1. + unmasked_channel_indices (list, *optional*): + Indices of channels that will not be masked. + channel_consistent_masking (bool, *optional*, defaults to `False`): + When true, masking will be same across all channels of a timeseries. Otherwise, masking positions will vary + across channels. + mask_value (int, *optional*, defaults to 0): + Define the value of masked patches for pretraining. + + Returns: + `tuple(torch.Tensor)`: inputs_mask, masked input, same shape as input Tensor and mask tensor of shape [bs x c x + n] + """ + if mask_ratio < 0 or mask_ratio >= 1: + raise ValueError(f"Mask ratio {mask_ratio} has to be between 0 and 1.") + + batch_size, num_channels, sequence_length, num_features = inputs.shape + device = inputs.device + + len_keep = int(sequence_length * (1 - mask_ratio)) + + if channel_consistent_masking: + noise = torch.rand(batch_size, 1, sequence_length, device=device) # noise in [0, 1], bs x 1 x L + noise = noise.repeat(1, num_channels, 1) # bs x num_channels x time + else: + # noise in [0, 1], bs x num_channels x L + noise = torch.rand(batch_size, num_channels, sequence_length, device=device) + + # mask: [bs x num_channels x num_patch] + mask = torch.ones(batch_size, num_channels, sequence_length, device=device) + mask[:, :, :len_keep] = 0 + + # sort noise for each sample + ids_shuffle = torch.argsort(noise, dim=-1) # ascend: small is keep, large is remove + ids_restore = torch.argsort(ids_shuffle, dim=-1) # ids_restore: [bs x num_channels x L] + + mask = torch.gather(mask, dim=-1, index=ids_restore) + mask = mask.unsqueeze(-1).repeat(1, 1, 1, num_features) # mask: [bs x num_channels x num_patches x patch_length] + if unmasked_channel_indices is not None: + mask[:, unmasked_channel_indices, :, :] = 0 + + inputs_mask = inputs.masked_fill(mask.bool(), mask_value) + return inputs_mask, mask[..., 0] + + +def forecast_masking( + inputs: torch.Tensor, + num_forecast_mask_patches: list | int, + unmasked_channel_indices: list | None = None, + mask_value: int = 0, +): + """Forecast masking that masks the last K patches where K is from the num_forecast_mask_patches. + If num_forecast_mask_patches is a list, samples in the batch will be randomly masked by numbers defined in the list. + + Parameters: + inputs (`torch.Tensor`): + Input of shape `(bs, num_channels, num_patch, patch_length)` + num_forecast_mask_patches (`list`): + Number of patches to be masked at the end of each batch sample. e.g. 4 or [3, 5]. + unmasked_channel_indices (`list`, *optional*): + Indices of channels that are not masked. + mask_value (`int`, *optional*, defaults to 0): + Values in the masked patches will be filled by `mask_value`. + + Returns: + `tuple(torch.Tensor)`: inputs_mask, masked input, same shape as inputs Tensor and Mask tensor of shape `(bs, + num_channels , num_patch)` or `(bs, tsg1, tsg2, num_channels, num_patch)` + """ + + if isinstance(num_forecast_mask_patches, int): + num_forecast_mask_patches = [num_forecast_mask_patches] + forecast_mask_ratios = [1 for _ in num_forecast_mask_patches] + + batch_size, num_channels, sequence_length, num_features = inputs.shape + mask = torch.zeros(batch_size, num_channels, sequence_length, device=inputs.device) + + t_list = [] + total_length = 0 + total_ratio = sum(forecast_mask_ratios) + + for patch_length, ratio in zip(num_forecast_mask_patches, forecast_mask_ratios): + if patch_length <= 0 or patch_length >= sequence_length: + raise ValueError( + f"num_forecast_mask_patches {patch_length} should be greater than 0 and less than total patches." + ) + temp_len = int(batch_size * ratio / total_ratio) + t_list.append([patch_length, ratio, temp_len]) + total_length += temp_len + + t_list = sorted(t_list, key=lambda x: x[2]) + + if total_length < batch_size: + t_list[0][2] = t_list[0][2] + (batch_size - total_length) + elif total_length > batch_size: + t_list[-1][2] = t_list[-1][2] + (total_length - batch_size) + + batch1 = 0 + for patch_len, _, temp_len in t_list: + batch2 = batch1 + temp_len + mask[batch1:batch2, :, -patch_len:] = 1 + batch1 = batch2 + + perm = torch.randperm(mask.shape[0]) + mask = mask[perm] + + mask = mask.unsqueeze(-1).repeat(1, 1, 1, num_features) # mask: [bs x num_channels x num_patch x patch_len] + if unmasked_channel_indices is not None: + mask[:, unmasked_channel_indices, :, :] = 0 + + inputs_mask = inputs.masked_fill(mask.bool(), mask_value) + return inputs_mask, mask[..., 0] + + +class PatchTSTPatchify(nn.Module): + """ + A class to patchify the time series sequence into different patches + + Returns: + `torch.Tensor` of shape `(batch_size, num_channels, num_patches, patch_length)` + """ + + def __init__(self, config: PatchTSTConfig): + super().__init__() + + self.sequence_length = config.context_length + self.patch_length = config.patch_length + self.patch_stride = config.patch_stride + + if self.sequence_length <= self.patch_length: + raise ValueError( + f"Sequence length ({self.sequence_length}) has to be greater than the patch length ({self.patch_length})" + ) + + # get the number of patches + self.num_patches = (max(self.sequence_length, self.patch_length) - self.patch_length) // self.patch_stride + 1 + new_sequence_length = self.patch_length + self.patch_stride * (self.num_patches - 1) + self.sequence_start = self.sequence_length - new_sequence_length + + def forward(self, past_values: torch.Tensor): + """ + Parameters: + past_values (`torch.Tensor` of shape `(batch_size, sequence_length, num_channels)`, *required*): + Input for patchification + + Returns: + `torch.Tensor` of shape `(batch_size, num_channels, num_patches, patch_length)` + """ + sequence_length = past_values.shape[-2] + if sequence_length != self.sequence_length: + raise ValueError( + f"Input sequence length ({sequence_length}) doesn't match model configuration ({self.sequence_length})." + ) + # output: [bs x new_sequence_length x num_channels] + output = past_values[:, self.sequence_start :, :] + # output: [bs x num_patches x num_input_channels x patch_length] + output = output.unfold(dimension=-2, size=self.patch_length, step=self.patch_stride) + # output: [bs x num_input_channels x num_patches x patch_length] + output = output.transpose(-2, -3).contiguous() + return output + + +class PatchTSTMasking(nn.Module): + """ + Class to perform random or forecast masking. + + Parameters: + config (`PatchTSTConfig`): model config + Returns: + x_mask (`torch.Tensor` of shape `(batch_size, num_channels, num_patches, patch_length)`) + Masked patched input + mask (`torch.Tensor` of shape `(batch_size, num_channels, num_patches)`) + Bool tensor indicating True on masked points + """ + + def __init__(self, config: PatchTSTConfig): + super().__init__() + self.random_mask_ratio = config.random_mask_ratio + self.channel_consistent_masking = config.channel_consistent_masking + self.mask_type = config.mask_type + self.num_forecast_mask_patches = config.num_forecast_mask_patches + self.unmasked_channel_indices = config.unmasked_channel_indices + self.mask_value = config.mask_value + if self.unmasked_channel_indices is not None: + self.unmasked_channel_indices = sorted(self.unmasked_channel_indices) + + def forward(self, patch_input: torch.Tensor): + """ + Parameters: + patch_input (`torch.Tensor` of shape `(batch_size, num_channels, num_patches, patch_length)`, *required*): + Patch input + + Return: + masked_input (`torch.Tensor` of shape `(batch_size, num_channels, num_patches, patch_length)`) + Masked patched input + mask (`torch.Tensor` of shape `(batch_size, num_channels, num_patches)`) + Bool tensor indicating True on masked points + + """ + if self.mask_type == "random": + masked_input, mask = random_masking( + inputs=patch_input, + mask_ratio=self.random_mask_ratio, + unmasked_channel_indices=self.unmasked_channel_indices, + channel_consistent_masking=self.channel_consistent_masking, + mask_value=self.mask_value, + ) + elif self.mask_type == "forecast": + masked_input, mask = forecast_masking( + inputs=patch_input, + num_forecast_mask_patches=self.num_forecast_mask_patches, + unmasked_channel_indices=self.unmasked_channel_indices, + mask_value=self.mask_value, + ) + else: + raise ValueError(f"Invalid mask type {self.mask_type}.") + + # mask: [bs x num_input_channels x num_patch] + mask = mask.bool() + return masked_input, mask + + +class PatchTSTEncoderLayer(nn.Module): + """ + PatchTST encoder layer + """ + + def __init__(self, config: PatchTSTConfig): + super().__init__() + + self.channel_attention = config.channel_attention + + self.self_attn = PatchTSTAttention( + embed_dim=config.d_model, + num_heads=config.num_attention_heads, + dropout=config.attention_dropout, + config=config, + ) + + # Add & Norm of the sublayer 1 + self.dropout_path1 = nn.Dropout(config.path_dropout) if config.path_dropout > 0 else nn.Identity() + if config.norm_type == "batchnorm": + self.norm_sublayer1 = PatchTSTBatchNorm(config) + elif config.norm_type == "layernorm": + self.norm_sublayer1 = nn.LayerNorm(config.d_model, eps=config.norm_eps) + else: + raise ValueError(f"{config.norm_type} is not a supported norm layer type.") + + # Add & Norm of the sublayer 2 + if self.channel_attention: + self.dropout_path2 = nn.Dropout(config.path_dropout) if config.path_dropout > 0 else nn.Identity() + if config.norm_type == "batchnorm": + self.norm_sublayer2 = PatchTSTBatchNorm(config) + elif config.norm_type == "layernorm": + self.norm_sublayer2 = nn.LayerNorm(config.d_model, eps=config.norm_eps) + else: + raise ValueError(f"{config.norm_type} is not a supported norm layer type.") + + # Position-wise Feed-Forward + self.ff = nn.Sequential( + nn.Linear(config.d_model, config.ffn_dim, bias=config.bias), + ACT2CLS[config.activation_function](), + nn.Dropout(config.ff_dropout) if config.ff_dropout > 0 else nn.Identity(), + nn.Linear(config.ffn_dim, config.d_model, bias=config.bias), + ) + + # Add & Norm of sublayer 3 + self.dropout_path3 = nn.Dropout(config.path_dropout) if config.path_dropout > 0 else nn.Identity() + if config.norm_type == "batchnorm": + self.norm_sublayer3 = PatchTSTBatchNorm(config) + elif config.norm_type == "layernorm": + self.norm_sublayer3 = nn.LayerNorm(config.d_model, eps=config.norm_eps) + else: + raise ValueError(f"{config.norm_type} is not a supported norm layer type.") + + self.pre_norm = config.pre_norm + + def forward(self, hidden_state: torch.Tensor, output_attentions: bool | None = None): + """ + Parameters: + hidden_state (`torch.Tensor` of shape `(batch_size, num_channels, sequence_length, d_model)`, *required*): + Past values of the time series + output_attentions (`bool`, *optional*): + Whether or not to return the output attention of all layers + Return: + `torch.Tensor` of shape `(batch_size, num_channels, sequence_length, d_model)` + + """ + batch_size, num_input_channels, sequence_length, d_model = hidden_state.shape + + # First sublayer: attention across time + # hidden_states: [(bs*num_channels) x sequence_length x d_model] + hidden_state = hidden_state.view(batch_size * num_input_channels, sequence_length, d_model) + + if self.pre_norm: + ## Norm and Multi-Head attention and Add residual connection + attn_output, attn_weights, _ = self.self_attn( + hidden_states=self.norm_sublayer1(hidden_state), output_attentions=output_attentions + ) + # Add: residual connection with residual dropout + hidden_state = hidden_state + self.dropout_path1(attn_output) + else: + ## Multi-Head attention and Add residual connection and Norm - Standard Transformer from BERT + attn_output, attn_weights, _ = self.self_attn( + hidden_states=hidden_state, output_attentions=output_attentions + ) + # hidden_states: [(bs*num_channels) x sequence_length x d_model] + hidden_state = self.norm_sublayer1(hidden_state + self.dropout_path1(attn_output)) + + # hidden_state: [bs x num_channels x sequence_length x d_model] + hidden_state = hidden_state.reshape(batch_size, num_input_channels, sequence_length, d_model) + + # second sublayer: attention across variable at any given time + if self.channel_attention: + # hidden_state: [bs x sequence_length x num_channels x d_model] + hidden_state = hidden_state.transpose(2, 1).contiguous() + # hidden_state: [(bs*sequence_length) x num_channels x d_model] + hidden_state = hidden_state.view(batch_size * sequence_length, num_input_channels, d_model) + if self.pre_norm: + ## Norm and Multi-Head attention and Add residual connection + attn_output, channel_attn_weights, _ = self.self_attn( + hidden_states=self.norm_sublayer2(hidden_state), output_attentions=output_attentions + ) + # Add: residual connection with residual dropout + hidden_state = hidden_state + self.dropout_path2(attn_output) + else: + ## Multi-Head attention and Add residual connection and Norm + attn_output, channel_attn_weights, _ = self.self_attn( + hidden_states=hidden_state, output_attentions=output_attentions + ) + # hidden_states: [(bs*sequence_length) x num_channels x d_model] + hidden_state = self.norm_sublayer2(hidden_state + self.dropout_path2(attn_output)) + + # Reshape hidden state + # hidden_state: [bs x sequence_length x num_channels x d_model] + hidden_state = hidden_state.reshape(batch_size, sequence_length, num_input_channels, d_model) + # hidden_state: [bs x num_channels x sequence_length x d_model] + hidden_state = hidden_state.transpose(1, 2).contiguous() + + # Third sublayer: mixing across hidden + # hidden_state: [(batch_size*num_channels) x sequence_length x d_model] + hidden_state = hidden_state.view(batch_size * num_input_channels, sequence_length, d_model) + if self.pre_norm: + ## Norm and Position-wise Feed-Forward and Add residual connection + # Add: residual connection with residual dropout + hidden_state = hidden_state + self.dropout_path3(self.ff(self.norm_sublayer3(hidden_state))) + else: + ## Position-wise Feed-Forward and Add residual connection and Norm + # Add: residual connection with residual dropout + hidden_state = self.norm_sublayer3(hidden_state + self.dropout_path3(self.ff(hidden_state))) + + # [bs x num_channels x sequence_length x d_model] + hidden_state = hidden_state.reshape(batch_size, num_input_channels, sequence_length, d_model) + + outputs = (hidden_state,) + if output_attentions: + outputs += (attn_weights, channel_attn_weights) if self.channel_attention else (attn_weights,) + + return outputs + + +@auto_docstring +class PatchTSTPreTrainedModel(PreTrainedModel): + config: PatchTSTConfig + base_model_prefix = "model" + main_input_name = "past_values" + input_modalities = ("time",) + supports_gradient_checkpointing = False + _supports_flash_attn = True + _supports_sdpa = True + _supports_flex_attn = True + + @torch.no_grad() + def _init_weights(self, module: nn.Module): + """ + Initialize weights + """ + if isinstance(module, PatchTSTPositionalEncoding): + # get the number of patches + num_patches = ( + max(self.config.context_length, self.config.patch_length) - self.config.patch_length + ) // self.config.patch_stride + 1 + # initialize cls_token + if self.config.use_cls_token: + init.normal_(module.cls_token, std=0.02) + num_patches += 1 + # initialize positional encoding + position_enc = module._init_pe(self.config, num_patches) + if is_deepspeed_zero3_enabled(): + import deepspeed + + with deepspeed.zero.GatheredParameters(module.position_enc, modifier_rank=None): + if module.position_enc.numel() > 0: + init.copy_(module.position_enc, position_enc) + else: + init.copy_(module.position_enc, position_enc) + elif isinstance(module, (nn.LayerNorm, nn.BatchNorm1d)): + init.zeros_(module.bias) + init.ones_(module.weight) + if getattr(module, "running_mean", None) is not None: + init.zeros_(module.running_mean) + init.ones_(module.running_var) + init.zeros_(module.num_batches_tracked) + elif isinstance(module, nn.Linear): + init.normal_(module.weight, mean=0.0, std=self.config.init_std) + if module.bias is not None: + init.zeros_(module.bias) + + def _set_gradient_checkpointing(self, module, value=False): + if isinstance(module, (PatchTSTEncoder)): + module.gradient_checkpointing = value + + +class PatchTSTEmbedding(nn.Module): + def __init__(self, config: PatchTSTConfig): + super().__init__() + self.num_input_channels = config.num_input_channels + self.share_embedding = config.share_embedding + # Input encoding: projection of feature vectors onto a d-dim vector space + if self.share_embedding: + self.input_embedding = nn.Linear(config.patch_length, config.d_model) + else: + self.input_embedding = nn.ModuleList() + for _ in range(config.num_input_channels): + self.input_embedding.append(nn.Linear(config.patch_length, config.d_model)) + + def forward(self, patch_input: torch.Tensor): + """ + Parameters: + patch_input (`torch.Tensor` of shape `(batch_size, num_channels, num_patches, patch_length)`, *required*): + Patch input for embedding + return: + `torch.Tensor` of shape `(batch_size, num_channels, num_patches, d_model)` + """ + # Input encoding + num_input_channels = patch_input.shape[1] + if num_input_channels != self.num_input_channels: + raise ValueError( + f"The defined number of input channels ({self.num_input_channels}) in the config " + f"has to be the same as the number of channels in the batch input ({num_input_channels})" + ) + if self.share_embedding: + embeddings = self.input_embedding(patch_input) # x: [bs x num_channels x num_patches x d_model] + else: + embeddings = [self.input_embedding[i](patch_input[:, i, :, :]) for i in range(num_input_channels)] + embeddings = torch.stack(embeddings, dim=1) + return embeddings + + +class PatchTSTPositionalEncoding(nn.Module): + """ + Class for positional encoding + """ + + def __init__(self, config: PatchTSTConfig, num_patches: int): + super().__init__() + self.use_cls_token = config.use_cls_token + self.num_input_channels = config.num_input_channels + if config.use_cls_token: + # cls_token: [1 x num_input_channels x 1 x d_model] + self.cls_token = nn.Parameter(torch.zeros(1, 1, 1, config.d_model)) + num_patches += 1 + # positional encoding: [num_patches x d_model] + self.position_enc = self._init_pe(config, num_patches) + # Positional dropout + self.positional_dropout = ( + nn.Dropout(config.positional_dropout) if config.positional_dropout > 0 else nn.Identity() + ) + + @staticmethod + def _init_pe(config: PatchTSTConfig, num_patches: int) -> nn.Parameter: + # Positional encoding + if config.positional_encoding_type == "random": + position_enc = nn.Parameter(torch.randn(num_patches, config.d_model), requires_grad=True) + elif config.positional_encoding_type == "sincos": + position_enc = torch.zeros(num_patches, config.d_model) + position = torch.arange(0, num_patches).unsqueeze(1) + div_term = torch.exp(torch.arange(0, config.d_model, 2) * -(math.log(10000.0) / config.d_model)) + position_enc[:, 0::2] = torch.sin(position * div_term) + position_enc[:, 1::2] = torch.cos(position * div_term) + position_enc = position_enc - position_enc.mean() + position_enc = position_enc / (position_enc.std() * 10) + position_enc = nn.Parameter(position_enc, requires_grad=False) + else: + raise ValueError( + f"{config.positional_encoding_type} is not a valid positional encoder. Available types are 'random' and 'sincos'." + ) + return position_enc + + def forward(self, patch_input: torch.Tensor): + if self.use_cls_token: + # patch_input: [bs x num_channels x num_patches x d_model] + patch_input = self.positional_dropout(patch_input + self.position_enc[1:, :]) + # append cls token where cls_token: [1 x num_channels x 1 x d_model] + cls_token = self.cls_token + self.position_enc[:1, :] + # get the same copy of cls_token for all the samples in batch: [bs x num_channels x 1 x d_model] + cls_tokens = cls_token.expand(patch_input.shape[0], self.num_input_channels, -1, -1) + # hidden_state: [bs x num_channels x (num_patches+1) x d_model] + hidden_state = torch.cat((cls_tokens, patch_input), dim=2) + else: + # hidden_state: [bs x num_channels x num_patches x d_model] + hidden_state = self.positional_dropout(patch_input + self.position_enc) + return hidden_state + + +class PatchTSTEncoder(PatchTSTPreTrainedModel): + """ + PatchTST Encoder + """ + + def __init__(self, config: PatchTSTConfig, num_patches: int): + super().__init__(config) + self.gradient_checkpointing = False + + # Input embedding: projection of feature vectors onto a d-dim vector space + self.embedder = PatchTSTEmbedding(config) + # Positional encoding + self.positional_encoder = PatchTSTPositionalEncoding(config, num_patches) + # Encoder + self.layers = nn.ModuleList([PatchTSTEncoderLayer(config) for i in range(config.num_hidden_layers)]) + + # Initialize weights and apply final processing + self.post_init() + + def forward( + self, + patch_input: torch.Tensor, + output_hidden_states: bool | None = None, + output_attentions: bool | None = None, + **kwargs, + ) -> BaseModelOutput: + """ + Parameters: + patch_input (`torch.Tensor` of shape `(batch_size, num_channels, num_patches, patch_length)`, *required*): + Past values of the time series + output_hidden_states (bool, optional): Indicates if hidden states should be outputted. + output_attentions (bool, optional): Indicates if attentions should be outputted. + + return: + `BaseModelOutput` + """ + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + + # Input embedding + patch_input = self.embedder(patch_input) + # Positional encoding + hidden_state = self.positional_encoder(patch_input) + + encoder_states = () if output_hidden_states else None + all_attentions = () if output_attentions else None + for encoder_layer in self.layers: + if output_hidden_states: + encoder_states = encoder_states + (hidden_state,) + + layer_outputs = encoder_layer(hidden_state=hidden_state, output_attentions=output_attentions) + # get hidden state. hidden_state shape is [bs x num_channels x num_patches x d_model] + # or [bs x num_channels x (num_patches+1) x d_model] if use cls_token + hidden_state = layer_outputs[0] + # append attention matrix at each layer + if output_attentions: + all_attentions = all_attentions + (layer_outputs[1],) + # return past_values, hidden_states + return BaseModelOutput(last_hidden_state=hidden_state, hidden_states=encoder_states, attentions=all_attentions) + + +@dataclass +@auto_docstring( + custom_intro=""" + Base class for model's outputs, with potential hidden states. + """ +) +class PatchTSTModelOutput(ModelOutput): + r""" + last_hidden_state (`torch.FloatTensor` of shape `(batch_size, num_channels, num_patches, patch_length)`): + Sequence of hidden-states at the output of the last layer of the model. + hidden_states (`tuple(torch.FloatTensor)`, *optional*, returned when `output_hidden_states=True` is passed or when `config.output_hidden_states=True`): + Tuple of `torch.FloatTensor` (one for the output of the embeddings, if the model has an embedding layer, + + one for the output of each layer) of shape `(batch_size, num_channels, height, width)`. Hidden-states of + the model at the output of each layer plus the optional initial embedding outputs. + mask (`torch.FloatTensor` of shape `(batch_size, num_channels, num_patches)`, *optional*): + Bool masked tensor indicating which patches are masked + loc (`torch.FloatTensor` of shape `(batch_size, 1, num_channels)`, *optional*): + Mean of the input data (batch_size, sequence_length, num_channels) over the sequence_length + scale (`torch.FloatTensor` of shape `(batch_size, 1, num_channels)`, *optional*): + Std of the input data (batch_size, sequence_length, num_channels) over the sequence_length + patch_input (`torch.FloatTensor` of shape `(batch_size, num_channels, num_patches, patch_length)`): + Patched input to the Transformer + """ + + last_hidden_state: torch.FloatTensor | None = None + hidden_states: tuple[torch.FloatTensor] | None = None + attentions: tuple[torch.FloatTensor] | None = None + mask: torch.FloatTensor | None = None + loc: torch.FloatTensor | None = None + scale: torch.FloatTensor | None = None + patch_input: torch.FloatTensor | None = None + + +@dataclass +@auto_docstring( + custom_intro=""" + Output type of [`PatchTSTForPretraining`]. + """ +) +class PatchTSTForPretrainingOutput(ModelOutput): + r""" + loss (*optional*, returned when `labels` is provided, `torch.FloatTensor` of shape `(1,)`): + MSE loss. + prediction_output (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.vocab_size)`): + Prediction outputs of the time series modeling heads. + """ + + loss: torch.FloatTensor | None = None + prediction_output: torch.FloatTensor | None = None + hidden_states: tuple[torch.FloatTensor] | None = None + attentions: tuple[torch.FloatTensor] | None = None + + +@dataclass +@auto_docstring( + custom_intro=""" + Output type of [`PatchTSTForRegression`]. + """ +) +class PatchTSTForRegressionOutput(ModelOutput): + r""" + loss (*optional*, returned when `labels` is provided, `torch.FloatTensor` of shape `(1,)`): + MSE loss. + regression_outputs (`torch.FloatTensor` of shape `(batch_size, num_targets)`): + Regression outputs of the time series modeling heads. + """ + + loss: torch.FloatTensor | None = None + regression_outputs: torch.FloatTensor | None = None + hidden_states: tuple[torch.FloatTensor] | None = None + attentions: tuple[torch.FloatTensor] | None = None + + +@dataclass +@auto_docstring( + custom_intro=""" + Output type of [`PatchTSTForPrediction`]. + """ +) +class PatchTSTForPredictionOutput(ModelOutput): + r""" + loss (*optional*, returned when `labels` is provided, `torch.FloatTensor` of shape `(1,)`): + MSE loss. + prediction_outputs (`torch.FloatTensor` of shape `(batch_size, prediction_length, -1)`): + Prediction outputs of the time series modeling heads. + attentions (`tuple(torch.FloatTensor)`, *optional*, returned when `output_attentions=True` is passed or when `config.output_attentions=True`): + Tuple of `torch.FloatTensor` (one for each layer) of shape `(batch_size, num_heads, sequence_length, + sequence_length)`. + + Attentions weights after the attention softmax, used to compute the weighted average in the self-attention + heads. + loc: (`torch.FloatTensor` of shape `(batch_size, 1, num_channels)`, *optional*) + Mean of the input data (batch_size, sequence_length, num_channels) over the sequence_length + scale: (`torch.FloatTensor` of shape `(batch_size, 1, num_channels)`, *optional*) + Std of the input data (batch_size, sequence_length, num_channels) over the sequence_length + """ + + loss: torch.FloatTensor | None = None + prediction_outputs: torch.FloatTensor | None = None + hidden_states: tuple[torch.FloatTensor] | None = None + attentions: tuple[torch.FloatTensor] | None = None + loc: torch.FloatTensor | None = None + scale: torch.FloatTensor | None = None + + +@dataclass +@auto_docstring( + custom_intro=""" + Output type of [`PatchTSTForClassification`]. + """ +) +class PatchTSTForClassificationOutput(ModelOutput): + r""" + loss (*optional*, returned when `labels` is provided, `torch.FloatTensor` of shape `(1,)`): + Total loss as the sum of the masked language modeling loss and the next sequence prediction + (classification) loss. + prediction_logits (`torch.FloatTensor` of shape `(batch_size, num_targets)`): + Prediction scores of the PatchTST modeling head (scores before SoftMax). + """ + + loss: torch.FloatTensor | None = None + prediction_logits: torch.FloatTensor | None = None + hidden_states: tuple[torch.FloatTensor] | None = None + attentions: tuple[torch.FloatTensor] | None = None + + +@dataclass +@auto_docstring( + custom_intro=""" + Base class for time series model's predictions outputs that contains the sampled values from the chosen + distribution. + """ +) +class SamplePatchTSTOutput(ModelOutput): + r""" + sequences (`torch.FloatTensor` of shape `(batch_size, num_samples, prediction_length, num_targets)`): + Sampled values from the chosen distribution. + """ + + sequences: torch.FloatTensor | None = None + + +# Copied from transformers.models.time_series_transformer.modeling_time_series_transformer.nll +def nll(input: torch.distributions.Distribution, target: torch.Tensor) -> torch.Tensor: + """ + Computes the negative log likelihood loss from input distribution with respect to target. + """ + return -input.log_prob(target) + + +# Copied from transformers.models.time_series_transformer.modeling_time_series_transformer.weighted_average +def weighted_average(input_tensor: torch.Tensor, weights: torch.Tensor | None = None, dim=None) -> torch.Tensor: + """ + Computes the weighted average of a given tensor across a given `dim`, masking values associated with weight zero, + meaning instead of `nan * 0 = nan` you will get `0 * 0 = 0`. + + Args: + input_tensor (`torch.FloatTensor`): + Input tensor, of which the average must be computed. + weights (`torch.FloatTensor`, *optional*): + Weights tensor, of the same shape as `input_tensor`. + dim (`int`, *optional*): + The dim along which to average `input_tensor`. + + Returns: + `torch.FloatTensor`: The tensor with values averaged along the specified `dim`. + """ + if weights is not None: + weighted_tensor = torch.where(weights != 0, input_tensor * weights, torch.zeros_like(input_tensor)) + sum_weights = torch.clamp(weights.sum(dim=dim) if dim else weights.sum(), min=1.0) + return (weighted_tensor.sum(dim=dim) if dim else weighted_tensor.sum()) / sum_weights + else: + return input_tensor.mean(dim=dim) + + +# Copied from transformers.models.time_series_transformer.modeling_time_series_transformer.TimeSeriesStdScaler with TimeSeriesTransformer->PatchTST,TimeSeries->PatchTST +class PatchTSTStdScaler(nn.Module): + """ + Standardize features by calculating the mean and scaling along the first dimension, and then normalizes it by + subtracting from the mean and dividing by the standard deviation. + """ + + def __init__(self, config: PatchTSTConfig): + super().__init__() + self.dim = config.scaling_dim if hasattr(config, "scaling_dim") else 1 + self.keepdim = config.keepdim if hasattr(config, "keepdim") else True + self.minimum_scale = config.minimum_scale if hasattr(config, "minimum_scale") else 1e-5 + + def forward( + self, data: torch.Tensor, observed_indicator: torch.Tensor + ) -> tuple[torch.Tensor, torch.Tensor, torch.Tensor]: + """ + Parameters: + data (`torch.Tensor` of shape `(batch_size, sequence_length, num_input_channels)`): + input for Batch norm calculation + observed_indicator (`torch.BoolTensor` of shape `(batch_size, sequence_length, num_input_channels)`): + Calculating the scale on the observed indicator. + Returns: + tuple of `torch.Tensor` of shapes + (`(batch_size, sequence_length, num_input_channels)`,`(batch_size, 1, num_input_channels)`, + `(batch_size, 1, num_input_channels)`) + """ + denominator = observed_indicator.sum(self.dim, keepdim=self.keepdim) + denominator = denominator.clamp_min(1.0) + loc = (data * observed_indicator).sum(self.dim, keepdim=self.keepdim) / denominator + + variance = (((data - loc) * observed_indicator) ** 2).sum(self.dim, keepdim=self.keepdim) / denominator + scale = torch.sqrt(variance + self.minimum_scale) + return (data - loc) / scale, loc, scale + + +# Copied from transformers.models.time_series_transformer.modeling_time_series_transformer.TimeSeriesMeanScaler with TimeSeriesTransformer->PatchTST,TimeSeries->PatchTST +class PatchTSTMeanScaler(nn.Module): + """ + Computes a scaling factor as the weighted average absolute value along the first dimension, and scales the data + accordingly. + """ + + def __init__(self, config: PatchTSTConfig): + super().__init__() + self.dim = config.scaling_dim if hasattr(config, "scaling_dim") else 1 + self.keepdim = config.keepdim if hasattr(config, "keepdim") else True + self.minimum_scale = config.minimum_scale if hasattr(config, "minimum_scale") else 1e-10 + self.default_scale = config.default_scale if hasattr(config, "default_scale") else None + + def forward( + self, data: torch.Tensor, observed_indicator: torch.Tensor + ) -> tuple[torch.Tensor, torch.Tensor, torch.Tensor]: + """ + Parameters: + data (`torch.Tensor` of shape `(batch_size, sequence_length, num_input_channels)`): + input for Batch norm calculation + observed_indicator (`torch.BoolTensor` of shape `(batch_size, sequence_length, num_input_channels)`): + Calculating the scale on the observed indicator. + Returns: + tuple of `torch.Tensor` of shapes + (`(batch_size, sequence_length, num_input_channels)`,`(batch_size, 1, num_input_channels)`, + `(batch_size, 1, num_input_channels)`) + """ + ts_sum = (data * observed_indicator).abs().sum(self.dim, keepdim=True) + num_observed = observed_indicator.sum(self.dim, keepdim=True) + + scale = ts_sum / torch.clamp(num_observed, min=1) + + # If `default_scale` is provided, we use it, otherwise we use the scale + # of the batch. + if self.default_scale is None: + batch_sum = ts_sum.sum(dim=0) + batch_observations = torch.clamp(num_observed.sum(0), min=1) + default_scale = torch.squeeze(batch_sum / batch_observations) + else: + default_scale = self.default_scale * torch.ones_like(scale) + + # apply default scale where there are no observations + scale = torch.where(num_observed > 0, scale, default_scale) + + # ensure the scale is at least `self.minimum_scale` + scale = torch.clamp(scale, min=self.minimum_scale) + scaled_data = data / scale + + if not self.keepdim: + scale = scale.squeeze(dim=self.dim) + + return scaled_data, torch.zeros_like(scale), scale + + +# Copied from transformers.models.time_series_transformer.modeling_time_series_transformer.TimeSeriesNOPScaler with TimeSeriesTransformer->PatchTST,TimeSeries->PatchTST +class PatchTSTNOPScaler(nn.Module): + """ + Assigns a scaling factor equal to 1 along the first dimension, and therefore applies no scaling to the input data. + """ + + def __init__(self, config: PatchTSTConfig): + super().__init__() + self.dim = config.scaling_dim if hasattr(config, "scaling_dim") else 1 + self.keepdim = config.keepdim if hasattr(config, "keepdim") else True + + def forward( + self, data: torch.Tensor, observed_indicator: torch.Tensor | None = None + ) -> tuple[torch.Tensor, torch.Tensor, torch.Tensor]: + """ + Parameters: + data (`torch.Tensor` of shape `(batch_size, sequence_length, num_input_channels)`): + input for Batch norm calculation + Returns: + tuple of `torch.Tensor` of shapes + (`(batch_size, sequence_length, num_input_channels)`,`(batch_size, 1, num_input_channels)`, + `(batch_size, 1, num_input_channels)`) + """ + scale = torch.ones_like(data, requires_grad=False).mean(dim=self.dim, keepdim=self.keepdim) + loc = torch.zeros_like(data, requires_grad=False).mean(dim=self.dim, keepdim=self.keepdim) + return data, loc, scale + + +class PatchTSTScaler(nn.Module): + def __init__(self, config: PatchTSTConfig): + super().__init__() + if config.scaling == "mean" or config.scaling is True: + self.scaler = PatchTSTMeanScaler(config) + elif config.scaling == "std": + self.scaler = PatchTSTStdScaler(config) + else: + self.scaler = PatchTSTNOPScaler(config) + + def forward( + self, data: torch.Tensor, observed_indicator: torch.Tensor + ) -> tuple[torch.Tensor, torch.Tensor, torch.Tensor]: + """ + Parameters: + data (`torch.Tensor` of shape `(batch_size, sequence_length, num_input_channels)`): + Input for scaler calculation + observed_indicator (`torch.BoolTensor` of shape `(batch_size, sequence_length, num_input_channels)`): + Calculating the scale on the observed indicator. + Returns: + tuple of `torch.Tensor` of shapes + (`(batch_size, sequence_length, num_input_channels)`,`(batch_size, 1, num_input_channels)`, + `(batch_size, 1, um_input_channels)`) + """ + data, loc, scale = self.scaler(data, observed_indicator) + return data, loc, scale + + +@auto_docstring +class PatchTSTModel(PatchTSTPreTrainedModel): + def __init__(self, config: PatchTSTConfig): + super().__init__(config) + + self.scaler = PatchTSTScaler(config) + self.patchifier = PatchTSTPatchify(config) + self.do_mask_input = config.do_mask_input + # get num_patches information from PatchTSTPatchify + num_patches = self.patchifier.num_patches + + if self.do_mask_input: + self.masking = PatchTSTMasking(config) + else: + self.masking = nn.Identity() + self.encoder = PatchTSTEncoder(config, num_patches=num_patches) + + # Initialize weights and apply final processing + self.post_init() + + def forward( + self, + past_values: torch.Tensor, + past_observed_mask: torch.Tensor | None = None, + future_values: torch.Tensor | None = None, + output_hidden_states: bool | None = None, + output_attentions: bool | None = None, + return_dict: bool | None = None, + **kwargs, + ) -> tuple | PatchTSTModelOutput: + r""" + Parameters: + past_values (`torch.Tensor` of shape `(bs, sequence_length, num_input_channels)`, *required*): + Input sequence to the model + past_observed_mask (`torch.BoolTensor` of shape `(batch_size, sequence_length, num_input_channels)`, *optional*): + Boolean mask to indicate which `past_values` were observed and which were missing. Mask values selected + in `[0, 1]`: + + - 1 for values that are **observed**, + - 0 for values that are **missing** (i.e. NaNs that were replaced by zeros). + future_values (`torch.BoolTensor` of shape `(batch_size, prediction_length, num_input_channels)`, *optional*): + Future target values associated with the `past_values` + output_hidden_states (`bool`, *optional*): + Whether or not to return the hidden states of all layers + output_attentions (`bool`, *optional*): + Whether or not to return the output attention of all layers + return_dict (`bool`, *optional*): + Whether or not to return a `ModelOutput` instead of a plain tuple. + + Returns: + `PatchTSTModelOutput` or tuple of `torch.Tensor` (if `return_dict`=False or `config.return_dict`=False) + + Examples: + + ```python + >>> from huggingface_hub import hf_hub_download + >>> import torch + >>> from transformers import PatchTSTModel + + >>> file = hf_hub_download( + ... repo_id="hf-internal-testing/etth1-hourly-batch", filename="train-batch.pt", repo_type="dataset" + ... ) + >>> batch = torch.load(file) + + >>> model = PatchTSTModel.from_pretrained("namctin/patchtst_etth1_pretrain") + + >>> # during training, one provides both past and future values + >>> outputs = model( + ... past_values=batch["past_values"], + ... future_values=batch["future_values"], + ... ) + + >>> last_hidden_state = outputs.last_hidden_state + ```""" + + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + + if past_observed_mask is None: + past_observed_mask = torch.ones_like(past_values) + + # x: tensor [bs x sequence_length x num_input_channels] + scaled_past_values, loc, scale = self.scaler(past_values, past_observed_mask) + + # patched_values: [bs x num_input_channels x num_patches x patch_length] for pretrain + patched_values = self.patchifier(scaled_past_values) + if self.do_mask_input: + masked_values, mask = self.masking(patched_values) + else: + masked_values, mask = self.masking(patched_values), None + + encoder_output = self.encoder( + patch_input=masked_values, output_hidden_states=output_hidden_states, output_attentions=output_attentions + ) + + if not return_dict: + outputs = (encoder_output.last_hidden_state, encoder_output.hidden_states, encoder_output.attentions) + outputs = outputs + (mask, loc, scale, patched_values) + return tuple(v for v in outputs if v is not None) + + return PatchTSTModelOutput( + last_hidden_state=encoder_output.last_hidden_state, + hidden_states=encoder_output.hidden_states, + attentions=encoder_output.attentions, + mask=mask, + loc=loc, + scale=scale, + patch_input=patched_values, + ) + + +class PatchTSTMaskPretrainHead(nn.Module): + """ + Pretraining head for mask modelling + """ + + def __init__(self, config: PatchTSTConfig): + super().__init__() + self.dropout = nn.Dropout(config.head_dropout) if config.head_dropout > 0 else nn.Identity() + self.linear = nn.Linear(config.d_model, config.patch_length) + self.use_cls_token = config.use_cls_token + + def forward(self, embedding: torch.Tensor) -> torch.Tensor: + """ + Parameters: + embedding (`torch.Tensor` of shape `(bs, num_channels, num_patches, d_model)` or + `(bs, num_channels, num_patches+1, d_model)` if `cls_token` is set to True, *required*): + Embedding from the model + Returns: + `torch.Tensor` of shape `(bs, num_channels, num_patches, d_model)` or + `(bs, num_channels, num_patches+1, d_model)` if `cls_token` is set to True + + """ + embedding = self.linear(self.dropout(embedding)) # [bs x num_channels x num_patches x patch_length] + if self.use_cls_token: + embedding = embedding[:, :, 1:, :] # remove the first cls token + return embedding + + +@auto_docstring( + custom_intro=""" + The PatchTST for pretrain model. + """ +) +class PatchTSTForPretraining(PatchTSTPreTrainedModel): + def __init__(self, config: PatchTSTConfig): + super().__init__(config) + + config.do_mask_input = True + self.model = PatchTSTModel(config=config) + self.head = PatchTSTMaskPretrainHead(config) + + # Initialize weights and apply final processing + self.post_init() + + def forward( + self, + past_values: torch.Tensor, + past_observed_mask: torch.Tensor | None = None, + output_hidden_states: bool | None = None, + output_attentions: bool | None = None, + return_dict: bool | None = None, + **kwargs, + ) -> tuple | PatchTSTForPretrainingOutput: + r""" + Parameters: + past_values (`torch.Tensor` of shape `(bs, sequence_length, num_input_channels)`, *required*): + Input sequence to the model + past_observed_mask (`torch.BoolTensor` of shape `(batch_size, sequence_length, num_input_channels)`, *optional*): + Boolean mask to indicate which `past_values` were observed and which were missing. Mask values selected + in `[0, 1]`: + + - 1 for values that are **observed**, + - 0 for values that are **missing** (i.e. NaNs that were replaced by zeros). + output_hidden_states (`bool`, *optional*): + Whether or not to return the hidden states of all layers + output_attentions (`bool`, *optional*): + Whether or not to return the output attention of all layers + return_dict (`bool`, *optional*): Whether or not to return a `ModelOutput` instead of a plain tuple. + + Returns: + `PatchTSTForPretrainingOutput` or tuple of `torch.Tensor` (if `return_dict`=False or + `config.return_dict`=False) + + Examples: + + ```python + >>> from huggingface_hub import hf_hub_download + >>> import torch + >>> from transformers import PatchTSTConfig, PatchTSTForPretraining + + >>> file = hf_hub_download( + ... repo_id="hf-internal-testing/etth1-hourly-batch", filename="train-batch.pt", repo_type="dataset" + ... ) + >>> batch = torch.load(file) + + >>> # Config for random mask pretraining + >>> config = PatchTSTConfig( + ... num_input_channels=7, + ... context_length=512, + ... patch_length=12, + ... stride=12, + ... mask_type='random', + ... random_mask_ratio=0.4, + ... use_cls_token=True, + ... ) + >>> # Config for forecast mask pretraining + >>> config = PatchTSTConfig( + ... num_input_channels=7, + ... context_length=512, + ... patch_length=12, + ... stride=12, + ... mask_type='forecast', + ... num_forecast_mask_patches=5, + ... use_cls_token=True, + ... ) + >>> model = PatchTSTForPretraining(config) + + >>> # during training, one provides both past and future values + >>> outputs = model(past_values=batch["past_values"]) + + >>> loss = outputs.loss + >>> loss.backward() + ```""" + + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + # past_values: [bs x num_channels x num_patches x d_model] or + # [bs x num_channels x (num_patches+1) x d_model] if use cls_token + model_output = self.model( + past_values=past_values, + past_observed_mask=past_observed_mask, + output_hidden_states=output_hidden_states, + output_attentions=output_attentions, + return_dict=True, + ) + + # last_hidden_state: [bs x num_channels x num_patches x patch_length] or + # [bs x num_channels x (num_patches+1) x patch_length] if use cls_token + x_hat = self.head(model_output.last_hidden_state) + + # calculate masked_loss + loss = nn.MSELoss(reduction="none") + loss_val = loss(x_hat, model_output.patch_input) + masked_loss = (loss_val.mean(dim=-1) * model_output.mask).sum() / (model_output.mask.sum() + 1e-10) + + encoder_states = model_output.hidden_states + if not return_dict: + outputs = (x_hat,) + model_output[1:-4] + outputs = (masked_loss,) + outputs if masked_loss is not None else outputs + return outputs + return PatchTSTForPretrainingOutput( + loss=masked_loss, prediction_output=x_hat, hidden_states=encoder_states, attentions=model_output.attentions + ) + + +class PatchTSTClassificationHead(nn.Module): + def __init__(self, config: PatchTSTConfig): + super().__init__() + self.use_cls_token = config.use_cls_token + self.pooling_type = config.pooling_type + self.flatten = nn.Flatten(start_dim=1) + self.dropout = nn.Dropout(config.head_dropout) if config.head_dropout > 0 else nn.Identity() + self.linear = nn.Linear(config.num_input_channels * config.d_model, config.num_targets) + + def forward(self, embedding: torch.Tensor): + """ + Parameters: + embedding (`torch.Tensor` of shape `(bs, num_channels, num_patches, d_model)` or + `(bs, num_channels, num_patches+1, d_model)` if `cls_token` is set to True, *required*): + Embedding from the model + Returns: + `torch.Tensor` of shape `(bs, num_targets)` + + """ + if self.use_cls_token: + # use the first output token, pooled_embedding: bs x num_channels x d_model + pooled_embedding = embedding[:, :, 0, :] + elif self.pooling_type == "mean": + # pooled_embedding: [bs x num_channels x d_model] + pooled_embedding = embedding.mean(dim=2) + elif self.pooling_type == "max": + # pooled_embedding: [bs x num_channels x d_model] + pooled_embedding = embedding.max(dim=2).values + else: + raise ValueError(f"pooling operator {self.pooling_type} is not implemented yet") + # pooled_embedding: bs x num_channels * d_model + pooled_embedding = self.flatten(pooled_embedding) + # output: bs x n_classes + output = self.linear(self.dropout(pooled_embedding)) + return output + + +@auto_docstring( + custom_intro=""" + The PatchTST for classification model. + """ +) +class PatchTSTForClassification(PatchTSTPreTrainedModel): + def __init__(self, config: PatchTSTConfig): + super().__init__(config) + + # Turn off masking + if config.do_mask_input: + logger.warning("Setting `do_mask_input` parameter to False.") + config.do_mask_input = False + + self.model = PatchTSTModel(config) + self.head = PatchTSTClassificationHead(config) + + # Initialize weights and apply final processing + self.post_init() + + @auto_docstring + def forward( + self, + past_values: torch.Tensor, + target_values: torch.Tensor | None = None, + past_observed_mask: bool | None = None, + output_hidden_states: bool | None = None, + output_attentions: bool | None = None, + return_dict: bool | None = None, + **kwargs, + ) -> tuple | PatchTSTForClassificationOutput: + r""" + past_values (`torch.Tensor` of shape `(bs, sequence_length, num_input_channels)`, *required*): + Input sequence to the model + target_values (`torch.Tensor`, *optional*): + Labels associates with the `past_values` + past_observed_mask (`torch.BoolTensor` of shape `(batch_size, sequence_length, num_input_channels)`, *optional*): + Boolean mask to indicate which `past_values` were observed and which were missing. Mask values selected + in `[0, 1]`: + + - 1 for values that are **observed**, + - 0 for values that are **missing** (i.e. NaNs that were replaced by zeros). + + Examples: + + ```python + >>> from transformers import PatchTSTConfig, PatchTSTForClassification + + >>> # classification task with two input channel2 and 3 classes + >>> config = PatchTSTConfig( + ... num_input_channels=2, + ... num_targets=3, + ... context_length=512, + ... patch_length=12, + ... stride=12, + ... use_cls_token=True, + ... ) + >>> model = PatchTSTForClassification(config=config) + + >>> # during inference, one only provides past values + >>> past_values = torch.randn(20, 512, 2) + >>> outputs = model(past_values=past_values) + >>> labels = outputs.prediction_logits + ```""" + + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + model_output = self.model( + past_values=past_values, + past_observed_mask=past_observed_mask, + output_hidden_states=output_hidden_states, + output_attentions=output_attentions, + return_dict=True, + ) + y_hat = self.head(model_output.last_hidden_state) + + loss_val = None + if target_values is not None: + loss = nn.CrossEntropyLoss() + loss_val = loss(y_hat, target_values) + + if not return_dict: + outputs = (y_hat,) + model_output[1:-3] + outputs = (loss_val,) + outputs if loss_val is not None else outputs + return outputs + return PatchTSTForClassificationOutput( + loss=loss_val, + prediction_logits=y_hat, + hidden_states=model_output.hidden_states, + attentions=model_output.attentions, + ) + + +@auto_docstring( + custom_intro=""" + The PatchTST for regression Model. + """ +) +class PatchTSTPredictionHead(nn.Module): + def __init__(self, config: PatchTSTConfig, num_patches: int, distribution_output=None): + r""" + num_patches (`int`): + The number of patches in the input sequence. + distribution_output (`DistributionOutput`, *optional*): + The distribution output layer for probabilistic forecasting. If None, a linear output layer is used. + """ + super().__init__() + + self.share_projection = config.share_projection + self.num_input_channels = config.num_input_channels + self.use_cls_token = config.use_cls_token + self.pooling_type = config.pooling_type + if self.pooling_type or self.use_cls_token: + head_dim = config.d_model + else: + head_dim = config.d_model * num_patches + + if not self.share_projection: + # if each channel has its own head + self.projections = nn.ModuleList() + self.dropouts = nn.ModuleList() + self.flattens = nn.ModuleList() + for i in range(self.num_input_channels): + self.flattens.append(nn.Flatten(start_dim=2)) + if distribution_output is None: + # use linear head + self.projections.append(nn.Linear(head_dim, config.prediction_length)) + else: + # use distribution head + self.projections.append(distribution_output.get_parameter_projection(head_dim)) + self.dropouts.append(nn.Dropout(config.head_dropout) if config.head_dropout > 0 else nn.Identity()) + else: + # all the channels share the same head + self.flatten = nn.Flatten(start_dim=2) + if distribution_output is None: + # use linear head + self.projection = nn.Linear(head_dim, config.prediction_length) + else: + # use distribution head + self.projection = distribution_output.get_parameter_projection(head_dim) + self.dropout = nn.Dropout(config.head_dropout) if config.head_dropout > 0 else nn.Identity() + + def forward(self, embedding: torch.Tensor): + """ + Parameters: + embedding (`torch.Tensor` of shape `(bs, num_channels, num_patches, d_model)` or + `(bs, num_channels, num_patches+1, d_model)` if `cls_token` is set to True, *required*): + Embedding from the model + Returns: + `torch.Tensor` of shape `(bs, forecast_len, num_channels)` + + """ + if self.use_cls_token: + # pooled_embedding: [bs x num_channels x d_model] + pooled_embedding = embedding[:, :, 0, :] + else: + if self.pooling_type == "mean": + # pooled_embedding: [bs x num_channels x d_model] + pooled_embedding = embedding.mean(dim=2) + elif self.pooling_type == "max": + # pooled_embedding: [bs x num_channels x d_model] + pooled_embedding = embedding.max(dim=2).values + else: + # pooled_embedding: [bs x num_channels x num_patches x d_model] + pooled_embedding = embedding + + if not self.share_projection: + output = [] + for i in range(self.num_input_channels): + # pooled_embedding: [bs x (d_model * num_patches)] or [bs x d_model)] + pooled_embedding = self.flattens[i](pooled_embedding[:, i, :]) + pooled_embedding = self.dropouts[i](pooled_embedding) + # pooled_embedding: [bs x forecast_len] + # or tuple ([bs x forecast_len], [bs x forecast_len]) if using distribution head + pooled_embedding = self.projections[i](pooled_embedding) + output.append(pooled_embedding) + # output: [bs x num_channels x forecast_len] + output = torch.stack(output, dim=1) + else: + # pooled_embedding: [bs x num_channels x (d_model * num_patches)] or [bs x num_channels x d_model)] + pooled_embedding = self.flatten(pooled_embedding) + pooled_embedding = self.dropout(pooled_embedding) + # output: [bs x num_channels x forecast_len] or + # tuple ([bs x num_channels x forecast_len], [bs x num_channels x forecast_len]) if using distribution head + output = self.projection(pooled_embedding) + + if isinstance(output, tuple): + # output: ([bs x forecast_len x num_channels], [bs x forecast_len x num_channels]) + output = tuple(z.transpose(2, 1) for z in output) + else: + output = output.transpose(2, 1) # [bs x forecast_len x num_channels] + return output + + +@auto_docstring( + custom_intro=""" + The PatchTST for prediction model. + """ +) +class PatchTSTForPrediction(PatchTSTPreTrainedModel): + def __init__(self, config: PatchTSTConfig): + super().__init__(config) + + # Turn off masking + if config.do_mask_input: + logger.warning("Setting `do_mask_input` parameter to False.") + config.do_mask_input = False + + self.model = PatchTSTModel(config) + + if config.loss == "mse": + self.distribution_output = None + else: + if config.distribution_output == "student_t": + self.distribution_output = StudentTOutput(dim=config.prediction_length) + elif config.distribution_output == "normal": + self.distribution_output = NormalOutput(dim=config.prediction_length) + elif config.distribution_output == "negative_binomial": + self.distribution_output = NegativeBinomialOutput(dim=config.prediction_length) + else: + raise ValueError(f"Unknown distribution output {config.distribution_output}") + + self.head = PatchTSTPredictionHead( + config, self.model.patchifier.num_patches, distribution_output=self.distribution_output + ) + + # Initialize weights and apply final processing + self.post_init() + + def forward( + self, + past_values: torch.Tensor, + past_observed_mask: torch.Tensor | None = None, + future_values: torch.Tensor | None = None, + output_hidden_states: bool | None = None, + output_attentions: bool | None = None, + return_dict: bool | None = None, + **kwargs, + ) -> tuple | PatchTSTForPredictionOutput: + r""" + Parameters: + past_values (`torch.Tensor` of shape `(bs, sequence_length, num_input_channels)`, *required*): + Input sequence to the model + past_observed_mask (`torch.BoolTensor` of shape `(batch_size, sequence_length, num_input_channels)`, *optional*): + Boolean mask to indicate which `past_values` were observed and which were missing. Mask values selected + in `[0, 1]`: + + - 1 for values that are **observed**, + - 0 for values that are **missing** (i.e. NaNs that were replaced by zeros). + future_values (`torch.Tensor` of shape `(bs, forecast_len, num_input_channels)`, *optional*): + Future target values associated with the `past_values` + output_hidden_states (`bool`, *optional*): + Whether or not to return the hidden states of all layers + output_attentions (`bool`, *optional*): + Whether or not to return the output attention of all layers + return_dict (`bool`, *optional*): + Whether or not to return a `ModelOutput` instead of a plain tuple. + + Returns: + `PatchTSTForPredictionOutput` or tuple of `torch.Tensor` (if `return_dict`=False or + `config.return_dict`=False) + + Examples: + + ```python + >>> from huggingface_hub import hf_hub_download + >>> import torch + >>> from transformers import PatchTSTConfig, PatchTSTForPrediction + + >>> file = hf_hub_download( + ... repo_id="hf-internal-testing/etth1-hourly-batch", filename="train-batch.pt", repo_type="dataset" + ... ) + >>> batch = torch.load(file) + + >>> # Prediction task with 7 input channels and prediction length is 96 + >>> model = PatchTSTForPrediction.from_pretrained("namctin/patchtst_etth1_forecast") + + >>> # during training, one provides both past and future values + >>> outputs = model( + ... past_values=batch["past_values"], + ... future_values=batch["future_values"], + ... ) + + >>> loss = outputs.loss + >>> loss.backward() + + >>> # during inference, one only provides past values, the model outputs future values + >>> outputs = model(past_values=batch["past_values"]) + >>> prediction_outputs = outputs.prediction_outputs + ```""" + + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + # get model output + model_output = self.model( + past_values=past_values, + past_observed_mask=past_observed_mask, + output_hidden_states=output_hidden_states, + output_attentions=output_attentions, + return_dict=True, + ) + # get output head + y_hat = self.head(model_output.last_hidden_state) + + loss_val = None + + if self.distribution_output: + y_hat_out = y_hat + else: + y_hat_out = y_hat * model_output.scale + model_output.loc + + if future_values is not None: + if self.distribution_output: + distribution = self.distribution_output.distribution( + y_hat, loc=model_output.loc, scale=model_output.scale + ) + loss_val = nll(distribution, future_values) + # take average of the loss + loss_val = weighted_average(loss_val) + else: + loss = nn.MSELoss(reduction="mean") + loss_val = loss(y_hat_out, future_values) + + loc = model_output.loc + scale = model_output.scale + + if not return_dict: + outputs = (y_hat_out,) + model_output[1:-1] + outputs = (loss_val,) + outputs if loss_val is not None else outputs + return outputs + return PatchTSTForPredictionOutput( + loss=loss_val, + prediction_outputs=y_hat_out, + hidden_states=model_output.hidden_states, + attentions=model_output.attentions, + loc=loc, + scale=scale, + ) + + @torch.no_grad() + def generate( + self, + past_values: torch.Tensor, + past_observed_mask: torch.Tensor | None = None, + ) -> SamplePatchTSTOutput: + """ + Generate sequences of sample predictions from a model with a probability distribution head. + + Parameters: + past_values (`torch.FloatTensor` of shape `(batch_size, sequence_length, num_input_channels)`): + Past values of the time series that serves as context in order to predict the future. + past_observed_mask (`torch.BoolTensor` of shape `(batch_size, sequence_length, num_input_channels)`, *optional*): + Boolean mask to indicate which `past_values` were observed and which were missing. Mask values selected + in `[0, 1]`: + + - 1 for values that are **observed**, + - 0 for values that are **missing** (i.e. NaNs that were replaced by zeros). + + Return: + [`SamplePatchTSTOutput`] where the outputs `sequences` tensor will have shape `(batch_size, number of + samples, prediction_length, 1)` or `(batch_size, number of samples, prediction_length, num_input_channels)` + for multivariate predictions. + """ + # get number of samples + num_parallel_samples = self.config.num_parallel_samples + + # get model output + outputs = self( + past_values=past_values, + future_values=None, + past_observed_mask=past_observed_mask, + output_hidden_states=False, + ) + if self.distribution_output: + # get distribution + distribution = self.distribution_output.distribution( + outputs.prediction_outputs, loc=outputs.loc, scale=outputs.scale + ) + # get samples: list of [bs x forecast_len x num_channels] + samples = [distribution.sample() for _ in range(num_parallel_samples)] + # samples: [bs x num_samples x forecast_len x num_channels] + samples = torch.stack(samples, dim=1) + else: + samples = outputs.prediction_outputs.unsqueeze(1) + + return SamplePatchTSTOutput(sequences=samples) + + +class PatchTSTRegressionHead(nn.Module): + """ + Regression head + """ + + def __init__(self, config: PatchTSTConfig, distribution_output=None): + super().__init__() + self.y_range = config.output_range + self.use_cls_token = config.use_cls_token + self.pooling_type = config.pooling_type + self.distribution_output = distribution_output + + head_dim = config.num_input_channels * config.d_model + + self.flatten = nn.Flatten(start_dim=1) + self.dropout = nn.Dropout(config.head_dropout) if config.head_dropout > 0 else nn.Identity() + + if distribution_output is None: + self.projection = nn.Linear(head_dim, config.num_targets) + else: + self.projection = distribution_output.get_parameter_projection(head_dim) + + def forward(self, embedding: torch.Tensor): + """ + Parameters: + embedding (`torch.Tensor` of shape `(bs, num_channels, num_patches, d_model)` or + `(bs, num_channels, num_patches+1, d_model)` if `cls_token` is set to True, *required*): + Embedding from the model + Returns: + `torch.Tensor` of shape `(bs, output_dim)` + + """ + if self.use_cls_token: + # use the first output token, pooled_embedding: [bs x num_channels x d_model] + pooled_embedding = embedding[:, :, 0, :] + elif self.pooling_type == "mean": + # pooled_embedding: [bs x num_channels x d_model] + pooled_embedding = embedding.mean(dim=2) + elif self.pooling_type == "max": + # pooled_embedding: [bs x num_channels x d_model] + pooled_embedding = embedding.max(dim=2).values + else: + raise ValueError(f"pooling operator {self.pooling_type} is not implemented yet") + # flatten the input + # pooled_embedding: bs x (num_channels * d_model) + pooled_embedding = self.dropout(self.flatten(pooled_embedding)) + # projection + # output: bs x output_dim or a tuple of this shape for distribution head + output = self.projection(pooled_embedding) + # apply sigmoid to bound the output if required + if (self.distribution_output is None) & (self.y_range is not None): # linear head + output = torch.sigmoid(output) * (self.y_range[1] - self.y_range[0]) + self.y_range[0] + return output + + +@auto_docstring( + custom_intro=""" + The PatchTST for regression model. + """ +) +class PatchTSTForRegression(PatchTSTPreTrainedModel): + def __init__(self, config: PatchTSTConfig): + super().__init__(config) + + # Turn off masking + if config.do_mask_input: + logger.warning("Setting `do_mask_input` parameter to False.") + config.do_mask_input = False + + self.model = PatchTSTModel(config) + if config.loss == "mse": + self.distribution_output = None + else: + if config.distribution_output == "student_t": + self.distribution_output = StudentTOutput(dim=config.num_targets) + elif config.distribution_output == "normal": + self.distribution_output = NormalOutput(dim=config.num_targets) + elif config.distribution_output == "negative_binomial": + self.distribution_output = NegativeBinomialOutput(dim=config.num_targets) + else: + raise ValueError(f"Unknown distribution output {config.distribution_output}") + + self.head = PatchTSTRegressionHead(config, self.distribution_output) + + # Initialize weights and apply final processing + self.post_init() + + @auto_docstring + def forward( + self, + past_values: torch.Tensor, + target_values: torch.Tensor | None = None, + past_observed_mask: torch.Tensor | None = None, + output_hidden_states: bool | None = None, + output_attentions: bool | None = None, + return_dict: bool | None = None, + **kwargs, + ) -> tuple | PatchTSTForRegressionOutput: + r""" + past_values (`torch.Tensor` of shape `(bs, sequence_length, num_input_channels)`, *required*): + Input sequence to the model + target_values (`torch.Tensor` of shape `(bs, num_input_channels)`): + Target values associates with the `past_values` + past_observed_mask (`torch.BoolTensor` of shape `(batch_size, sequence_length, num_input_channels)`, *optional*): + Boolean mask to indicate which `past_values` were observed and which were missing. Mask values selected + in `[0, 1]`: + + - 1 for values that are **observed**, + - 0 for values that are **missing** (i.e. NaNs that were replaced by zeros). + Whether or not to return a `ModelOutput` instead of a plain tuple. + + Examples: + + ```python + >>> from transformers import PatchTSTConfig, PatchTSTForRegression + + >>> # Regression task with 6 input channels and regress 2 targets + >>> model = PatchTSTForRegression.from_pretrained("namctin/patchtst_etth1_regression") + + >>> # during inference, one only provides past values, the model outputs future values + >>> past_values = torch.randn(20, 512, 6) + >>> outputs = model(past_values=past_values) + >>> regression_outputs = outputs.regression_outputs + ```""" + + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + model_output = self.model( + past_values=past_values, + past_observed_mask=past_observed_mask, + output_hidden_states=output_hidden_states, + output_attentions=output_attentions, + return_dict=True, + ) + # get output head. y_hat is of shape [bs x num_targets] or tuple of this shape + y_hat = self.head(model_output.last_hidden_state) + + loss = None + if target_values is not None: + if self.distribution_output: + distribution = self.distribution_output.distribution(y_hat) + # y_hat should be a 2-tuple, each with dimension [bs, num_targets] + y_hat = tuple(item.view(-1, self.config.num_targets) for item in y_hat) + loss = nll(distribution, target_values) + # take average of the loss + loss = weighted_average(loss) + else: + loss = nn.MSELoss(reduction="mean") + loss = loss(y_hat, target_values) + + if not return_dict: + # hidden_states, attentions, mask + outputs = (y_hat,) + model_output[1:-3] + outputs = (loss,) + outputs if loss is not None else outputs + return outputs + return PatchTSTForRegressionOutput( + loss=loss, + regression_outputs=y_hat, + hidden_states=model_output.hidden_states, + attentions=model_output.attentions, + ) + + @torch.no_grad() + def generate( + self, + past_values: torch.Tensor, + past_observed_mask: torch.Tensor | None = None, + ) -> SamplePatchTSTOutput: + """ + Generate sequences of sample predictions from a model with a probability distribution head. + + Parameters: + past_values (`torch.FloatTensor` of shape `(batch_size, sequence_length, num_input_channels)`): + Past values of the time series that serves as context in order to predict the future. + past_observed_mask (`torch.BoolTensor` of shape `(batch_size, sequence_length, num_input_channels)`, *optional*): + Boolean mask to indicate which `past_values` were observed and which were missing. Mask values selected + in `[0, 1]`: + + - 1 for values that are **observed**, + - 0 for values that are **missing** (i.e. NaNs that were replaced by zeros). + + Return: + [`SamplePatchTSTOutput`] where the outputs `sequences` tensor will have shape `(batch_size, number of + samples, num_targets)`. + """ + # get number of samples + num_parallel_samples = self.config.num_parallel_samples + + # get model output + outputs = self( + past_values=past_values, + target_values=None, + past_observed_mask=past_observed_mask, + output_hidden_states=False, + ) + + # get distribution + distribution = self.distribution_output.distribution(outputs.regression_outputs) + # get samples: list of [bs x num_targets] + samples = [distribution.sample() for _ in range(num_parallel_samples)] + # samples: [bs x num_samples x num_targets] + samples = torch.stack(samples, dim=1).view(-1, num_parallel_samples, self.config.num_targets) + return SamplePatchTSTOutput(sequences=samples) + + +__all__ = [ + "PatchTSTModel", + "PatchTSTPreTrainedModel", + "PatchTSTForPrediction", + "PatchTSTForPretraining", + "PatchTSTForRegression", + "PatchTSTForClassification", +] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pe_audio/__init__.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pe_audio/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..dead10e3f5de486207f4e2f513a50ca51f877ba9 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pe_audio/__init__.py @@ -0,0 +1,29 @@ +# Copyright 2025 the HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from typing import TYPE_CHECKING + +from ...utils import _LazyModule +from ...utils.import_utils import define_import_structure + + +if TYPE_CHECKING: + from .configuration_pe_audio import * + from .feature_extraction_pe_audio import * + from .modeling_pe_audio import * + from .processing_pe_audio import * +else: + import sys + + _file = globals()["__file__"] + sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__) diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pe_audio/configuration_pe_audio.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pe_audio/configuration_pe_audio.py new file mode 100644 index 0000000000000000000000000000000000000000..ada93c46e98e1085670c79f45906d889b0e767b8 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pe_audio/configuration_pe_audio.py @@ -0,0 +1,204 @@ +# Copyright 2025 the HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +from ...configuration_utils import PreTrainedConfig, PretrainedConfig +from ...modeling_rope_utils import RopeParameters +from ...utils import logging +from ..auto import CONFIG_MAPPING, AutoConfig + + +logger = logging.get_logger(__name__) + + +class PeAudioEncoderConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`PeAudioEncoder`]. It is used to instantiate a + PeAudioEncoder model according to the specified arguments, defining the model architecture. Instantiating a configuration + with the defaults will yield a similar configuration to that of pe-av-large. + e.g. [facebook/pe-av-large](https://huggingface.co/facebook/pe-av-large) + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + + Args: + dac_config (`Union[PreTrainedConfig, dict]`, *optional*): + Configuration for the DAC audio encoder used to tokenize the raw audio inputs. If a dictionary is passed, it + will be used to instantiate a [`~transformers.DacConfig`] with default DAC hyperparameters. + hidden_size (`int`, *optional*, defaults to 1792): + Dimension of the hidden representations. + intermediate_size (`int`, *optional*, defaults to 4800): + Dimension of the feedforward layers in the Transformer blocks. + num_hidden_layers (`int`, *optional*, defaults to 6): + Number of Transformer encoder blocks. + num_attention_heads (`int`, *optional*, defaults to 14): + Number of attention heads used in each attention layer. + num_key_value_heads (`int`, *optional*): + Number of key and value heads for grouped-query attention. If unset, this defaults to `num_attention_heads`. + head_dim (`int`, *optional*, defaults to 128): + Dimension of each attention head for query, key, and value projections. + hidden_act (`str`, *optional*, defaults to `"silu"`): + The non-linear activation function (function or string) in the Transformer blocks. + max_position_embeddings (`int`, *optional*, defaults to 10000): + Maximum sequence length supported by the rotary position embeddings. + initializer_range (`float`, *optional*, defaults to 0.02): + Standard deviation of the truncated normal initializer for weight matrices. + rms_norm_eps (`float`, *optional*, defaults to 1e-05): + Epsilon used by the RMS normalization layers. + rope_parameters (`Union[RopeParameters, dict]`, *optional*, defaults to `{'rope_theta': 20000}`): + Parameters for the rotary position embeddings, such as the base `rope_theta`. + attention_bias (`bool`, *optional*, defaults to `False`): + Whether to use bias terms in the query, key, value, and output projections. + attention_dropout (`float`, *optional*, defaults to 0.0): + Dropout ratio applied to attention probabilities. + + ```python + >>> from transformers import PeAudioEncoder, PeAudioEncoderConfig + + >>> # Initializing a PeAudioEncoder style configuration + >>> configuration = PeAudioEncoderConfig() + + >>> # Initializing a model from the pe-av-large style configuration + >>> model = PeAudioEncoder(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "pe_audio_encoder" + sub_configs = {"dac_config": AutoConfig} + base_config_key = "audio_video_config" + + _default_dac_config_kwargs = { + "downsampling_ratios": [2, 8, 10, 12], + "encoder_hidden_size": 64, + "codebook_dim": 128, + } + + def __init__( + self, + dac_config: dict | PreTrainedConfig | None = None, + hidden_size: int | None = 1792, + intermediate_size: int | None = 4800, + num_hidden_layers: int | None = 6, + num_attention_heads: int | None = 14, + num_key_value_heads: int | None = None, + head_dim: int | None = 128, + hidden_act: str | None = "silu", + max_position_embeddings: int | None = 10000, + initializer_range: float | None = 0.02, + rms_norm_eps: float | None = 1e-5, + rope_parameters: RopeParameters | dict | None = {"rope_theta": 20000}, + attention_bias: bool | None = False, + attention_dropout: float | None = 0.0, + **kwargs, + ): + self.hidden_size = hidden_size + self.intermediate_size = intermediate_size + self.num_hidden_layers = num_hidden_layers + self.num_attention_heads = num_attention_heads + + # for backward compatibility + if num_key_value_heads is None: + num_key_value_heads = num_attention_heads + + self.num_key_value_heads = num_key_value_heads + self.head_dim = head_dim + self.hidden_act = hidden_act + self.max_position_embeddings = max_position_embeddings + self.initializer_range = initializer_range + self.rms_norm_eps = rms_norm_eps + self.rope_parameters = rope_parameters + self.attention_bias = attention_bias + self.attention_dropout = attention_dropout + + if isinstance(dac_config, dict): + dac_config["model_type"] = dac_config.get("model_type", "dac") + dac_config = CONFIG_MAPPING[dac_config["model_type"]](**{**self._default_dac_config_kwargs, **dac_config}) + elif dac_config is None: + dac_config = CONFIG_MAPPING["dac"](**self._default_dac_config_kwargs) + + self.dac_config = dac_config + + super().__init__(**kwargs) + + +class PeAudioConfig(PretrainedConfig): + r""" + This is the configuration class to store the configuration of a [`PeAudioModel`]. It is used to instantiate a + PeAudioModel model according to the specified arguments, defining the model architecture. Instantiating a configuration + with the defaults will yield a similar configuration to that of pe-av-large. + e.g. [facebook/pe-av-large](https://huggingface.co/facebook/pe-av-large) + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + + Args: + text_config (`dict` or `PreTrainedConfig`, *optional*): + Configuration for the text model component. + audio_config (`dict` or `PreTrainedConfig`, *optional*): + Configuration for the audio encoder component. + + ```python + >>> from transformers import PeAudioModel, PeAudioConfig + + >>> # Initializing a PeAudioModel style configuration + >>> configuration = PeAudioConfig() + + >>> # Initializing a model from the pe-av-large style configuration + >>> model = PeAudioModel(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "pe_audio" + sub_configs = {"text_config": AutoConfig, "audio_config": PeAudioEncoderConfig} + base_config_key = "audio_video_config" + + _default_text_config_kwargs = { + "model_type": "modernbert", + "hidden_size": 1024, + "intermediate_size": 2624, + "num_hidden_layers": 22, + "num_attention_heads": 16, + } + + def __init__( + self, + text_config=None, + audio_config=None, + **kwargs, + ): + if isinstance(text_config, dict): + text_config["model_type"] = text_config.get("model_type", "modernbert") + text_config = CONFIG_MAPPING[text_config["model_type"]]( + **{**self._default_text_config_kwargs, **text_config} + ) + elif text_config is None: + text_config = CONFIG_MAPPING["modernbert"](**self._default_text_config_kwargs) + + if isinstance(audio_config, dict): + audio_config = PeAudioEncoderConfig(**audio_config) + elif audio_config is None: + audio_config = PeAudioEncoderConfig() + + self.text_config = text_config + self.audio_config = audio_config + + super().__init__(**kwargs) + + +__all__ = ["PeAudioEncoderConfig", "PeAudioConfig"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pe_audio/feature_extraction_pe_audio.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pe_audio/feature_extraction_pe_audio.py new file mode 100644 index 0000000000000000000000000000000000000000..a7738d3089ac601acf746f992c84595ff9e2847a --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pe_audio/feature_extraction_pe_audio.py @@ -0,0 +1,160 @@ +# Copyright 2025 the HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import numpy as np + +from ...feature_extraction_sequence_utils import SequenceFeatureExtractor +from ...feature_extraction_utils import BatchFeature +from ...processing_utils import load_audio +from ...utils import PaddingStrategy, TensorType, logging + + +logger = logging.get_logger(__name__) + + +class PeAudioFeatureExtractor(SequenceFeatureExtractor): + r""" + Constructs a PeAudioFeatureExtractor feature extractor. + + This feature extractor inherits from [`~feature_extraction_sequence_utils.SequenceFeatureExtractor`] which contains + most of the main methods. Users should refer to this superclass for more information regarding those methods. + + Args: + feature_size (`int`, *optional*, defaults to 1): + The feature dimension of the extracted features. Use 1 for mono, 2 for stereo. + sampling_rate (`int`, *optional*, defaults to 48000): + The sampling rate at which the audio waveform should be digitalized, expressed in hertz (Hz). + padding_value (`float`, *optional*, defaults to 0.0): + The value that is used for padding. + hop_length (`int`, *optional*, defaults to 1920): + Overlap length between successive windows. + """ + + model_input_names = ["input_values"] + + def __init__( + self, + feature_size: int = 1, + sampling_rate: int = 48_000, + padding_value: float = 0.0, + hop_length: int = 1920, + **kwargs, + ): + super().__init__(feature_size=feature_size, sampling_rate=sampling_rate, padding_value=padding_value, **kwargs) + self.hop_length = hop_length + + def _reflect_pad(self, wav): + if len(wav) % self.hop_length == 0: + return wav + p1d = (0, self.hop_length - (len(wav) % self.hop_length)) + return np.pad(wav, p1d, "reflect") + + def __call__( + self, + raw_audio: np.ndarray | list[float] | list[np.ndarray] | list[list[float]] | str | list[str], + padding: bool | str | PaddingStrategy | None = None, + truncation: bool | None = False, + max_length: int | None = None, + return_tensors: str | TensorType | None = None, + sampling_rate: int | None = None, + ) -> BatchFeature: + from_file = False + if isinstance(raw_audio, str): + raw_audio = [raw_audio] + + if isinstance(raw_audio, (list, tuple)) and isinstance(raw_audio[0], str): + loaded = [] + for audio_file in raw_audio: + loaded.append(load_audio(audio_file, self.sampling_rate)) + raw_audio = loaded + from_file = True + + if sampling_rate is not None: + if sampling_rate != self.sampling_rate: + raise ValueError( + f"The model corresponding to this feature extractor: {self} was trained using a sampling rate of" + f" {self.sampling_rate}. Please make sure that the provided audio input was sampled with" + f" {self.sampling_rate} and not {sampling_rate}." + ) + elif not from_file: + logger.warning( + f"It is strongly recommended to pass the `sampling_rate` argument to `{self.__class__.__name__}()`. " + "Failing to do so can result in silent errors that might be hard to debug." + ) + + if padding and truncation: + raise ValueError("Both padding and truncation were set. Make sure you only set one.") + elif padding is None: + # by default let's pad the inputs + padding = True + + is_batched = bool( + isinstance(raw_audio, (list, tuple)) and (isinstance(raw_audio[0], (np.ndarray, tuple, list))) + ) + + if is_batched: + raw_audio = [np.asarray(audio, dtype=np.float32).T for audio in raw_audio] + elif not is_batched and not isinstance(raw_audio, np.ndarray): + raw_audio = np.asarray(raw_audio, dtype=np.float32) + elif isinstance(raw_audio, np.ndarray) and raw_audio.dtype is np.dtype(np.float64): + raw_audio = raw_audio.astype(np.float32) + + # always return batch + if not is_batched: + raw_audio = [np.asarray(raw_audio).T] + + if isinstance(raw_audio, list): + raw_audio = [self._reflect_pad(x) for x in raw_audio] + else: + raw_audio = self._reflect_pad(raw_audio) + + # verify inputs are valid + for example in raw_audio: + if example.ndim > 2: + raise ValueError(f"Expected input shape (channels, length) but got shape {example.shape}") + if self.feature_size == 1 and example.ndim != 1: + raise ValueError(f"Expected mono audio but example has {example.shape[-1]} channels") + if self.feature_size == 2: + raise ValueError("Stereo audio isn't supported for now") + + input_values = BatchFeature({"input_values": raw_audio}) + + # normal padding on batch + padded_inputs = self.pad( + input_values, + max_length=max_length, + truncation=truncation, + padding=padding, + return_attention_mask=padding, + pad_to_multiple_of=self.hop_length, + ) + if padding: + padded_inputs["padding_mask"] = padded_inputs.pop("attention_mask") + if padding: + padded_inputs.input_values = padded_inputs.input_values[:, np.newaxis, :] + + input_values = [] + for example in padded_inputs.pop("input_values"): + if self.feature_size == 1: + example = example[..., None] + input_values.append(example.T) + + padded_inputs["input_values"] = input_values + if return_tensors is not None: + padded_inputs = padded_inputs.convert_to_tensors(return_tensors) + + return padded_inputs + + +__all__ = ["PeAudioFeatureExtractor"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pe_audio/modeling_pe_audio.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pe_audio/modeling_pe_audio.py new file mode 100644 index 0000000000000000000000000000000000000000..5f58130e2146bee80c89fc9c6fc1fe82f4760b09 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pe_audio/modeling_pe_audio.py @@ -0,0 +1,826 @@ +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# This file was automatically generated from src/transformers/models/pe_audio/modular_pe_audio.py. +# Do NOT edit this file manually as any edits will be overwritten by the generation of +# the file from the modular. If any change should be done, please apply the change to the +# modular_pe_audio.py file directly. One of our CI enforces this. +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# Copyright 2025 the HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +import math +from collections.abc import Callable +from dataclasses import dataclass +from typing import Any, Optional + +import torch +import torch.nn as nn +import torch.nn.functional as F + +from ... import initialization as init +from ...activations import ACT2FN +from ...cache_utils import Cache +from ...configuration_utils import PreTrainedConfig +from ...integrations import use_kernel_forward_from_hub, use_kernelized_func +from ...masking_utils import create_bidirectional_mask +from ...modeling_layers import GradientCheckpointingLayer +from ...modeling_outputs import BaseModelOutputWithPooling, MaskedLMOutput +from ...modeling_rope_utils import ROPE_INIT_FUNCTIONS, dynamic_rope_update +from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel +from ...processing_utils import Unpack +from ...utils import ModelOutput, TransformersKwargs, auto_docstring, can_return_tuple +from ...utils.generic import maybe_autocast, merge_with_config_defaults +from ...utils.output_capturing import capture_outputs +from ..auto import AutoModel +from .configuration_pe_audio import PeAudioConfig, PeAudioEncoderConfig + + +class Snake1d(nn.Module): + """ + A 1-dimensional Snake activation function module. + """ + + def __init__(self, hidden_dim): + super().__init__() + self.alpha = nn.Parameter(torch.ones(1, hidden_dim, 1)) + + def forward(self, hidden_states): + shape = hidden_states.shape + hidden_states = hidden_states.reshape(shape[0], shape[1], -1) + hidden_states = hidden_states + (self.alpha + 1e-9).reciprocal() * torch.sin(self.alpha * hidden_states).pow(2) + hidden_states = hidden_states.reshape(shape) + return hidden_states + + +class PeAudioDacResidualUnit(nn.Module): + """ + A residual unit composed of Snake1d and weight-normalized Conv1d layers with dilations. + """ + + def __init__(self, dimension: int = 16, dilation: int = 1): + super().__init__() + pad = ((7 - 1) * dilation) // 2 + + self.snake1 = Snake1d(dimension) + self.conv1 = nn.Conv1d(dimension, dimension, kernel_size=7, dilation=dilation, padding=pad) + self.snake2 = Snake1d(dimension) + self.conv2 = nn.Conv1d(dimension, dimension, kernel_size=1) + + def forward(self, hidden_state): + """ + Forward pass through the residual unit. + + Args: + hidden_state (`torch.Tensor` of shape `(batch_size, channels, time_steps)`): + Input tensor . + + Returns: + output_tensor (`torch.Tensor` of shape `(batch_size, channels, time_steps)`): + Input tensor after passing through the residual unit. + """ + output_tensor = hidden_state + output_tensor = self.conv1(self.snake1(output_tensor)) + output_tensor = self.conv2(self.snake2(output_tensor)) + + padding = (hidden_state.shape[-1] - output_tensor.shape[-1]) // 2 + if padding > 0: + hidden_state = hidden_state[..., padding:-padding] + output_tensor = hidden_state + output_tensor + return output_tensor + + +class PeAudioDacEncoderBlock(nn.Module): + """Encoder block used in PE_AUDIO_DAC encoder.""" + + def __init__(self, config: PreTrainedConfig, stride: int = 1, stride_index: int = 1): + super().__init__() + + dimension = config.encoder_hidden_size * 2**stride_index + self.res_unit1 = PeAudioDacResidualUnit(dimension // 2, dilation=1) + self.res_unit2 = PeAudioDacResidualUnit(dimension // 2, dilation=3) + self.res_unit3 = PeAudioDacResidualUnit(dimension // 2, dilation=9) + self.snake1 = Snake1d(dimension // 2) + self.conv1 = nn.Conv1d( + dimension // 2, dimension, kernel_size=2 * stride, stride=stride, padding=math.ceil(stride / 2) + ) + + def forward(self, hidden_state): + hidden_state = self.res_unit1(hidden_state) + hidden_state = self.res_unit2(hidden_state) + hidden_state = self.snake1(self.res_unit3(hidden_state)) + hidden_state = self.conv1(hidden_state) + + return hidden_state + + +class PeAudioDacEncoder(nn.Module): + """PE_AUDIO_DAC Encoder""" + + def __init__(self, config: PreTrainedConfig): + super().__init__() + + strides = config.downsampling_ratios + # Create first convolution + self.conv1 = nn.Conv1d(1, config.encoder_hidden_size, kernel_size=7, padding=3) + + self.block = [] + # Create EncoderBlocks that double channels as they downsample by `stride` + for stride_index, stride in enumerate(strides): + stride_index = stride_index + 1 + self.block += [PeAudioDacEncoderBlock(config, stride=stride, stride_index=stride_index)] + + self.block = nn.ModuleList(self.block) + d_model = config.encoder_hidden_size * 2**stride_index + self.snake1 = Snake1d(d_model) + self.conv2 = nn.Conv1d(d_model, config.hidden_size, kernel_size=3, padding=1) + + def forward(self, hidden_state): + hidden_state = self.conv1(hidden_state) + + for module in self.block: + hidden_state = module(hidden_state) + + hidden_state = self.snake1(hidden_state) + hidden_state = self.conv2(hidden_state) + + return hidden_state + + +class PeAudioEncoderEmbedder(nn.Module): + def __init__(self, config: PeAudioEncoderConfig): + super().__init__() + self.dac_encoder = PeAudioDacEncoder(config.dac_config) + self.bottleneck = nn.Conv1d(config.dac_config.hidden_size, config.dac_config.codebook_dim, 1) + self.data_proj = nn.Linear(config.dac_config.codebook_dim, config.hidden_size) + self.config = config + + def forward( + self, + input_values: torch.Tensor, + padding_mask: torch.Tensor | None = None, + ) -> tuple[torch.Tensor, torch.Tensor | None]: + with torch.no_grad(), torch.backends.cudnn.flags(enabled=False): + hidden_states = self.dac_encoder(input_values) + hidden_states = self.bottleneck(hidden_states) + + codec_features = hidden_states.transpose(1, 2) + inputs_embeds = self.data_proj(codec_features) + + if padding_mask is not None: + padding_mask = padding_mask[:, :: self.config.dac_config.hop_length] + + return inputs_embeds, padding_mask + + +class PeAudioContrastiveHead(nn.Module): + def __init__( + self, + in_dim: int, + out_dim: int, + ) -> None: + super().__init__() + self.layer_norm = nn.LayerNorm(normalized_shape=in_dim, eps=1e-6) + self.proj = nn.Linear(in_dim, out_dim, bias=False) + + def forward(self, x: torch.Tensor) -> torch.FloatTensor: + return self.proj(self.layer_norm(x)) + + +class PeAudioMaskedGroupNorm(nn.GroupNorm): + def forward(self, x, padding_mask=None): + if padding_mask is None: + return super().forward(x) + + batch_size, hidden_size, seq_len = x.shape + group_size = hidden_size // self.num_groups + grouped_shape = (batch_size, -1, group_size, seq_len) + + x_grouped = x.view(grouped_shape) + padding_mask_grouped = padding_mask.reshape(grouped_shape).bool() + + mean = torch.masked.mean(x_grouped, mask=padding_mask_grouped, dim=(2, 3), keepdim=True) + var = torch.masked.var(x_grouped, mask=padding_mask_grouped, dim=(2, 3), keepdim=True, unbiased=False) + + x_norm = (x_grouped - mean) / torch.sqrt(var + self.eps) + x_norm = x_norm.view(x.shape) + + if self.affine: + x_norm = x_norm * self.weight.view(1, -1, 1) + self.bias.view(1, -1, 1) + + return x_norm * padding_mask + + +class PeAudioConvBlock1d(nn.Module): + def __init__(self, config): + super().__init__() + self.groupnorm = PeAudioMaskedGroupNorm(num_groups=1, num_channels=config.hidden_size) + self.activation = nn.SiLU() + self.project = nn.Conv1d( + in_channels=config.hidden_size, + out_channels=config.hidden_size, + kernel_size=3, + padding="same", + ) + + def forward(self, x, padding_mask=None): + x = self.groupnorm(x, padding_mask=padding_mask) + x = self.activation(x) + return self.project(x) + + +class PeAudioResnetBlock1d(nn.Module): + def __init__(self, config): + super().__init__() + self.block1 = PeAudioConvBlock1d(config) + self.block2 = PeAudioConvBlock1d(config) + + def forward(self, hidden_states, padding_mask=None): + """ + Args: + hidden_states: (batch_size, seq_len, hidden_size) + padding_mask: (batch_size, seq_len) + Returns: + hidden_states: (batch_size, seq_len, hidden_size) + """ + # transpose for convolutions + # (batch_size, seq_len, hidden_size) -> (batch_size, hidden_size, seq_len) + hidden_states = hidden_states.transpose(1, 2) + + if padding_mask is not None: + padding_mask = padding_mask.unsqueeze(1).expand_as(hidden_states) + + residual = hidden_states + hidden_states = self.block1(hidden_states, padding_mask=padding_mask) + hidden_states = self.block2(hidden_states, padding_mask=padding_mask) + hidden_states = residual + hidden_states + + return hidden_states.transpose(1, 2) + + +class PeAudioEncoderPatchEmbedder(nn.Module): + def __init__(self, config): + super().__init__() + self.resnet_block = PeAudioResnetBlock1d(config) + self.class_embedding = nn.Parameter(torch.randn(1, 1, config.hidden_size)) + + def forward(self, inputs_embeds, padding_mask=None): + # Embedding step: prepend class token and run the ResNet block. + hidden_states = torch.cat( + [self.class_embedding.expand(inputs_embeds.size(0), -1, -1), inputs_embeds], + dim=1, + ) + + if padding_mask is not None: + # TODO: any reason why we take padding_mask[0] and not just 1? + padding_mask = torch.cat([padding_mask[:, [0]], padding_mask], dim=1) + + hidden_states = self.resnet_block(hidden_states, padding_mask=padding_mask) + return hidden_states, padding_mask + + +def repeat_kv(hidden_states: torch.Tensor, n_rep: int) -> torch.Tensor: + """ + This is the equivalent of torch.repeat_interleave(x, dim=1, repeats=n_rep). The hidden states go from (batch, + num_key_value_heads, seqlen, head_dim) to (batch, num_attention_heads, seqlen, head_dim) + """ + batch, num_key_value_heads, slen, head_dim = hidden_states.shape + if n_rep == 1: + return hidden_states + hidden_states = hidden_states[:, :, None, :, :].expand(batch, num_key_value_heads, n_rep, slen, head_dim) + return hidden_states.reshape(batch, num_key_value_heads * n_rep, slen, head_dim) + + +def eager_attention_forward( + module: nn.Module, + query: torch.Tensor, + key: torch.Tensor, + value: torch.Tensor, + attention_mask: torch.Tensor | None, + scaling: float, + dropout: float = 0.0, + **kwargs: Unpack[TransformersKwargs], +): + key_states = repeat_kv(key, module.num_key_value_groups) + value_states = repeat_kv(value, module.num_key_value_groups) + + attn_weights = torch.matmul(query, key_states.transpose(2, 3)) * scaling + if attention_mask is not None: + attn_weights = attn_weights + attention_mask + + attn_weights = nn.functional.softmax(attn_weights, dim=-1, dtype=torch.float32).to(query.dtype) + attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training) + attn_output = torch.matmul(attn_weights, value_states) + attn_output = attn_output.transpose(1, 2).contiguous() + + return attn_output, attn_weights + + +def stack_freqs(cos: torch.Tensor, sin: torch.Tensor): + dim = cos.size(-1) + cos = cos.narrow(-1, 0, dim // 2) + sin = sin.narrow(-1, 0, dim // 2) + freqs_cis = torch.stack((cos, -sin, sin, cos), dim=-1).view(*cos.size(), 2, 2) + return freqs_cis + + +def apply_rotary_pos_emb(q, k, cos, sin, unsqueeze_dim=1): + freqs_cis = stack_freqs(cos, sin) + freqs_cis = freqs_cis.unsqueeze(unsqueeze_dim) + q_ = q.reshape(*q.shape[:-1], -1, 1, 2) + k_ = k.reshape(*k.shape[:-1], -1, 1, 2) + return (q_ * freqs_cis).sum(5).flatten(3), (k_ * freqs_cis).sum(5).flatten(3) + + +@use_kernel_forward_from_hub("RMSNorm") +class PeAudioEncoderRMSNorm(nn.Module): + def __init__(self, hidden_size, eps: float = 1e-6) -> None: + """ + PeAudioEncoderRMSNorm is equivalent to T5LayerNorm + """ + super().__init__() + self.weight = nn.Parameter(torch.ones(hidden_size)) + self.variance_epsilon = eps + + def forward(self, hidden_states: torch.Tensor) -> torch.Tensor: + input_dtype = hidden_states.dtype + hidden_states = hidden_states.to(torch.float32) + variance = hidden_states.pow(2).mean(-1, keepdim=True) + hidden_states = hidden_states * torch.rsqrt(variance + self.variance_epsilon) + return self.weight * hidden_states.to(input_dtype) + + def extra_repr(self): + return f"{tuple(self.weight.shape)}, eps={self.variance_epsilon}" + + +@use_kernelized_func(apply_rotary_pos_emb) +class PeAudioEncoderAttention(nn.Module): + """Multi-headed attention from 'Attention Is All You Need' paper""" + + def __init__(self, config, layer_idx): + super().__init__() + self.layer_type = config.layer_types[layer_idx] if hasattr(config, "layer_types") else None + self.config = config + self.layer_idx = layer_idx + self.head_dim = getattr(config, "head_dim", config.hidden_size // config.num_attention_heads) + self.num_key_value_groups = config.num_attention_heads // config.num_key_value_heads + self.scaling = self.head_dim**-0.5 + self.attention_dropout = config.attention_dropout + self.is_causal = False + + self.q_proj = nn.Linear( + config.hidden_size, config.num_attention_heads * self.head_dim, bias=config.attention_bias + ) + self.k_proj = nn.Linear( + config.hidden_size, config.num_key_value_heads * self.head_dim, bias=config.attention_bias + ) + self.v_proj = nn.Linear( + config.hidden_size, config.num_key_value_heads * self.head_dim, bias=config.attention_bias + ) + self.o_proj = nn.Linear( + config.num_attention_heads * self.head_dim, config.hidden_size, bias=config.attention_bias + ) + self.q_norm = PeAudioEncoderRMSNorm( + self.head_dim, eps=config.rms_norm_eps + ) # unlike olmo, only on the head dim! + self.k_norm = PeAudioEncoderRMSNorm( + self.head_dim, eps=config.rms_norm_eps + ) # thus post q_norm does not need reshape + + def forward( + self, + hidden_states: torch.Tensor, + position_embeddings: tuple[torch.Tensor, torch.Tensor] | None = None, + attention_mask: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor, torch.Tensor]: + input_shape = hidden_states.shape[:-1] + hidden_shape = (*input_shape, -1, self.head_dim) + + query_states = self.q_norm(self.q_proj(hidden_states).view(hidden_shape)).transpose(1, 2) + key_states = self.k_norm(self.k_proj(hidden_states).view(hidden_shape)).transpose(1, 2) + value_states = self.v_proj(hidden_states).view(hidden_shape).transpose(1, 2) + + cos, sin = position_embeddings + query_states, key_states = apply_rotary_pos_emb(query_states, key_states, cos, sin) + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, eager_attention_forward + ) + + attn_output, attn_weights = attention_interface( + self, + query_states, + key_states, + value_states, + attention_mask, + dropout=0.0 if not self.training else self.attention_dropout, + scaling=self.scaling, + **kwargs, + ) + + attn_output = attn_output.reshape(*input_shape, -1).contiguous() + attn_output = self.o_proj(attn_output) + return attn_output, attn_weights + + +class PeAudioEncoderMLP(nn.Module): + def __init__(self, config): + super().__init__() + self.config = config + self.hidden_size = config.hidden_size + self.intermediate_size = config.intermediate_size + self.gate_proj = nn.Linear(self.hidden_size, self.intermediate_size, bias=False) + self.up_proj = nn.Linear(self.hidden_size, self.intermediate_size, bias=False) + self.down_proj = nn.Linear(self.intermediate_size, self.hidden_size, bias=False) + self.act_fn = ACT2FN[config.hidden_act] + + def forward(self, x): + down_proj = self.down_proj(self.act_fn(self.gate_proj(x)) * self.up_proj(x)) + return down_proj + + +class PeAudioEncoderLayer(GradientCheckpointingLayer): + def __init__(self, config, layer_idx): + super().__init__() + self.hidden_size = config.hidden_size + + self.self_attn = PeAudioEncoderAttention(config=config, layer_idx=layer_idx) + + self.mlp = PeAudioEncoderMLP(config) + self.input_layernorm = PeAudioEncoderRMSNorm(config.hidden_size, eps=config.rms_norm_eps) + self.post_attention_layernorm = PeAudioEncoderRMSNorm(config.hidden_size, eps=config.rms_norm_eps) + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.Tensor | None = None, + position_ids: torch.LongTensor | None = None, + past_key_values: Cache | None = None, + use_cache: bool | None = False, + cache_position: torch.LongTensor | None = None, + position_embeddings: tuple[torch.Tensor, torch.Tensor] | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> torch.Tensor: + residual = hidden_states + hidden_states = self.input_layernorm(hidden_states) + # Self Attention + hidden_states, _ = self.self_attn( + hidden_states=hidden_states, + attention_mask=attention_mask, + position_ids=position_ids, + past_key_values=past_key_values, + use_cache=use_cache, + cache_position=cache_position, + position_embeddings=position_embeddings, + **kwargs, + ) + hidden_states = residual + hidden_states + + # Fully Connected + residual = hidden_states + hidden_states = self.post_attention_layernorm(hidden_states) + hidden_states = self.mlp(hidden_states) + hidden_states = residual + hidden_states + return hidden_states + + +@auto_docstring +class PeAudioPreTrainedModel(PreTrainedModel): + config: PeAudioConfig + base_model_prefix = "audio_model" + supports_gradient_checkpointing = True + _no_split_modules = ["PeAudioEncoderLayer"] + _skip_keys_device_placement = ["past_key_values"] + _supports_flash_attn = True + _supports_sdpa = True + _supports_flex_attn = True + + _can_compile_fullgraph = True + _supports_attention_backend = True + _can_record_outputs = { + "hidden_states": PeAudioEncoderLayer, + "attentions": PeAudioEncoderAttention, + } + + @torch.no_grad() + def _init_weights(self, module): + super()._init_weights(module) + + if hasattr(self.config, "initializer_range"): + std = self.config.initializer_range + else: + # 0.02 is the standard default value across the library + std = getattr(self.config.get_text_config(), "initializer_range", 0.02) + + if isinstance(module, PeAudioEncoderPatchEmbedder): + embed_dim = module.class_embedding.shape[-1] + init.normal_(module.class_embedding, mean=0.0, std=embed_dim**-0.5 * std) + if isinstance(module, nn.Conv1d): + init.trunc_normal_(module.weight, std=0.02) + init.constant_(module.bias, 0) + elif isinstance(module, Snake1d): + init.ones_(module.alpha) + elif isinstance(module, nn.ConvTranspose1d): + module.reset_parameters() + elif isinstance(module, nn.Embedding): + init.normal_(module.weight, mean=0.0, std=0.02) + + +@dataclass +@auto_docstring( + custom_intro=""" + Class for outputs of [`PeAudioEncoder`]. + """ +) +class PeAudioEncoderOutput(BaseModelOutputWithPooling): + codec_features: torch.FloatTensor | None = None + output_mask: tuple[torch.FloatTensor] | None = None + + +class PeAudioEncoderRotaryEmbedding(nn.Module): + inv_freq: torch.Tensor # fix linting for `register_buffer` + + def __init__(self, config: PeAudioEncoderConfig, device=None): + super().__init__() + self.max_seq_len_cached = config.max_position_embeddings + self.original_max_seq_len = config.max_position_embeddings + + self.config = config + + self.rope_type = self.config.rope_parameters["rope_type"] + rope_init_fn: Callable = self.compute_default_rope_parameters + if self.rope_type != "default": + rope_init_fn = ROPE_INIT_FUNCTIONS[self.rope_type] + inv_freq, self.attention_scaling = rope_init_fn(self.config, device) + + self.register_buffer("inv_freq", inv_freq, persistent=False) + self.register_buffer("original_inv_freq", inv_freq.clone(), persistent=False) + + @staticmethod + def compute_default_rope_parameters( + config: PeAudioEncoderConfig | None = None, + device: Optional["torch.device"] = None, + seq_len: int | None = None, + ) -> tuple["torch.Tensor", float]: + """ + Computes the inverse frequencies according to the original RoPE implementation + Args: + config ([`~transformers.PreTrainedConfig`]): + The model configuration. + device (`torch.device`): + The device to use for initialization of the inverse frequencies. + seq_len (`int`, *optional*): + The current sequence length. Unused for this type of RoPE. + Returns: + Tuple of (`torch.Tensor`, `float`), containing the inverse frequencies for the RoPE embeddings and the + post-processing scaling factor applied to the computed cos/sin (unused in this type of RoPE). + """ + base = config.rope_parameters["rope_theta"] + dim = getattr(config, "head_dim", None) or config.hidden_size // config.num_attention_heads + + attention_factor = 1.0 # Unused in this type of RoPE + + # Compute the inverse frequencies + inv_freq = 1.0 / ( + base ** (torch.arange(0, dim, 2, dtype=torch.int64).to(device=device, dtype=torch.float) / dim) + ) + return inv_freq, attention_factor + + @torch.no_grad() + @dynamic_rope_update # power user: used with advanced RoPE types (e.g. dynamic rope) + def forward(self, x, position_ids): + inv_freq_expanded = self.inv_freq[None, :, None].float().expand(position_ids.shape[0], -1, 1).to(x.device) + position_ids_expanded = position_ids[:, None, :].float() + + device_type = x.device.type if isinstance(x.device.type, str) and x.device.type != "mps" else "cpu" + with maybe_autocast(device_type=device_type, enabled=False): # Force float32 + freqs = (inv_freq_expanded.float() @ position_ids_expanded.float()).transpose(1, 2) + emb = torch.cat((freqs, freqs), dim=-1) + cos = emb.cos() * self.attention_scaling + sin = emb.sin() * self.attention_scaling + + return cos.to(dtype=x.dtype), sin.to(dtype=x.dtype) + + +@auto_docstring( + custom_intro=""" + The PeAudio Encoder model. + """ +) +class PeAudioEncoder(PeAudioPreTrainedModel): + config: PeAudioEncoderConfig + main_input_name = "input_values" + base_model_prefix = "audio_model.audio_encoder" + + def __init__(self, config: PeAudioEncoderConfig): + super().__init__(config) + self.embedder = PeAudioEncoderEmbedder(config) + self.patch_embedder = PeAudioEncoderPatchEmbedder(config) + self.layers = nn.ModuleList( + [PeAudioEncoderLayer(config, layer_idx) for layer_idx in range(config.num_hidden_layers)] + ) + self.norm = PeAudioEncoderRMSNorm(config.hidden_size, eps=config.rms_norm_eps) + self.rotary_emb = PeAudioEncoderRotaryEmbedding(config=config) + self.output = nn.Linear(config.hidden_size, config.hidden_size, bias=False) + self.gradient_checkpointing = False + + self.post_init() + + @can_return_tuple + @merge_with_config_defaults + @capture_outputs + def forward( + self, + input_values: torch.Tensor, + padding_mask: torch.Tensor | None = None, + **kwargs, + ) -> tuple | BaseModelOutputWithPooling: + inputs_embeds, padding_mask = self.embedder(input_values, padding_mask=padding_mask) + inputs_embeds, attention_mask = self.patch_embedder(inputs_embeds, padding_mask=padding_mask) + + if attention_mask is not None: + attention_mask = create_bidirectional_mask( + config=self.config, + inputs_embeds=inputs_embeds, + attention_mask=attention_mask, + ) + + position_ids = torch.arange(inputs_embeds.shape[1], device=inputs_embeds.device).unsqueeze(0) + position_embeddings = self.rotary_emb(inputs_embeds, position_ids) + + hidden_states = inputs_embeds + for encoder_layer in self.layers[: self.config.num_hidden_layers]: + hidden_states = encoder_layer( + hidden_states, + attention_mask=attention_mask, + position_embeddings=position_embeddings, + **kwargs, + ) + + hidden_states = self.norm(hidden_states) + hidden_states = self.output(hidden_states) + + return PeAudioEncoderOutput( + last_hidden_state=hidden_states[:, 1:], + pooler_output=hidden_states[:, 0], + output_mask=padding_mask, + ) + + +# TODO: not sure about the typing for text_model_output +@dataclass +# @auto_docstring +class PeAudioOutput(ModelOutput): + loss: torch.FloatTensor | None = None + logits_audio_text: torch.FloatTensor | None = None + text_audio_embeds: torch.FloatTensor | None = None + audio_embeds: torch.FloatTensor | None = None + text_outputs: BaseModelOutputWithPooling = None + audio_outputs: BaseModelOutputWithPooling = None + + def to_tuple(self) -> tuple[Any]: + return tuple( + self[k] if k not in ["text_outputs", "audio_outputs"] else getattr(self, k).to_tuple() for k in self.keys() + ) + + +class PeAudioModel(PeAudioPreTrainedModel): + def __init__(self, config: PeAudioConfig): + super().__init__(config) + self.text_model = AutoModel.from_config(config.text_config) + self.audio_encoder = PeAudioEncoder(config.audio_config) + + self.text_audio_head = PeAudioContrastiveHead(config.text_config.hidden_size, config.text_config.hidden_size) + self.audio_head = PeAudioContrastiveHead(config.audio_config.hidden_size, config.text_config.hidden_size) + + self.text_audio_logit_scale = nn.Parameter(torch.zeros(1)) + self.text_audio_logit_bias = nn.Parameter(torch.zeros(1)) + + self.post_init() + + def get_text_audio_embeds(self, input_ids, attention_mask=None): + # TODO: naming can be improved here... + text_outputs: MaskedLMOutput = self.text_model( + input_ids=input_ids, + attention_mask=attention_mask, + return_dict=True, + ) + text_audio_embeds = text_outputs.hidden_states[-1][:, 0] + return self.text_audio_head(text_audio_embeds) + + def get_audio_embeds(self, input_values, padding_mask=None): + audio_outputs: BaseModelOutputWithPooling = self.audio_encoder( + input_values=input_values, + padding_mask=padding_mask, + return_dict=True, + ) + audio_embeds = audio_outputs.pooler_output + return self.audio_head(audio_embeds) + + @can_return_tuple + def forward( + self, + input_ids: torch.Tensor, + input_values: torch.Tensor, + attention_mask: torch.Tensor | None = None, + padding_mask: torch.Tensor | None = None, + return_loss: bool | None = None, + **kwargs, + ) -> PeAudioOutput: + audio_outputs: BaseModelOutputWithPooling = self.audio_encoder( + input_values=input_values, padding_mask=padding_mask, **kwargs + ) + + kwargs["output_hidden_states"] = True + text_outputs: MaskedLMOutput = self.text_model(input_ids=input_ids, attention_mask=attention_mask, **kwargs) + + audio_embeds = audio_outputs.pooler_output + audio_embeds = self.audio_head(audio_embeds) + + text_audio_embeds = text_outputs.hidden_states[-1][:, 0] + text_audio_embeds = self.text_audio_head(text_audio_embeds) + + logits_audio_text = audio_embeds @ text_audio_embeds.T + logits_audio_text = logits_audio_text * self.text_audio_logit_scale.to( + logits_audio_text.device + ) + self.text_audio_logit_bias.to(logits_audio_text.device) + + loss = None + if return_loss: + labels = torch.eye(logits_audio_text.shape[0], device=logits_audio_text.device) + loss = -F.logsigmoid(labels * logits_audio_text).sum() / logits_audio_text.shape[0] + + return PeAudioOutput( + logits_audio_text=logits_audio_text, + text_audio_embeds=text_audio_embeds, + audio_embeds=audio_embeds, + text_outputs=text_outputs, + audio_outputs=audio_outputs, + loss=loss, + ) + + +# TODO: underline in documentation that logits output shape is +# 1. Model: (n_audio, n_text) +# 2. Frame-level: (n_audio, n_text, n_frames) +class PeAudioFrameLevelModel(PeAudioModel): + def get_audio_embeds(self, input_values, padding_mask=None): + audio_outputs: BaseModelOutputWithPooling = self.audio_encoder( + input_values=input_values, + padding_mask=padding_mask, + return_dict=True, + ) + audio_embeds = audio_outputs.last_hidden_state + audio_embeds = self.audio_head(audio_embeds) + return audio_embeds + + @can_return_tuple + def forward( + self, + input_ids: torch.Tensor, + input_values: torch.Tensor, + attention_mask: torch.Tensor | None = None, + padding_mask: torch.Tensor | None = None, + return_loss: bool | None = None, + **kwargs, + ) -> PeAudioOutput: + audio_outputs: BaseModelOutputWithPooling = self.audio_encoder( + input_values=input_values, padding_mask=padding_mask, **kwargs + ) + kwargs["output_hidden_states"] = True + text_outputs: MaskedLMOutput = self.text_model(input_ids=input_ids, attention_mask=attention_mask, **kwargs) + + audio_embeds = audio_outputs.last_hidden_state + audio_embeds = self.audio_head(audio_embeds) + + text_audio_embeds = text_outputs.hidden_states[-1][:, 0] + text_audio_embeds = self.text_audio_head(text_audio_embeds) + + logits_audio_text = (audio_embeds @ text_audio_embeds.T).transpose(1, 2) + logits_audio_text = logits_audio_text * self.text_audio_logit_scale + self.text_audio_logit_bias + + loss = None + if return_loss: + labels = torch.eye(logits_audio_text.shape[0], device=logits_audio_text.device) + loss = -F.logsigmoid(labels * logits_audio_text).sum() / logits_audio_text.shape[0] + + return PeAudioOutput( + logits_audio_text=logits_audio_text, + text_audio_embeds=text_audio_embeds, + audio_embeds=audio_embeds, + text_outputs=text_outputs, + audio_outputs=audio_outputs, + loss=loss, + ) + + +__all__ = ["PeAudioFrameLevelModel", "PeAudioModel", "PeAudioEncoder"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pe_audio/modular_pe_audio.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pe_audio/modular_pe_audio.py new file mode 100644 index 0000000000000000000000000000000000000000..8233367a3e37e66a704554e130347348d0962be1 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pe_audio/modular_pe_audio.py @@ -0,0 +1,306 @@ +# Copyright 2025 the HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from dataclasses import dataclass +from typing import Any + +import torch +import torch.nn as nn +import torch.nn.functional as F + +from ... import initialization as init +from ...configuration_utils import PreTrainedConfig +from ...masking_utils import create_bidirectional_mask +from ...modeling_outputs import BaseModelOutputWithPooling, MaskedLMOutput +from ...utils import ModelOutput, auto_docstring, can_return_tuple +from ...utils.generic import merge_with_config_defaults +from ...utils.output_capturing import capture_outputs +from ..auto import AutoModel +from ..dac.modeling_dac import DacEncoder, DacEncoderBlock, Snake1d +from ..pe_audio_video.modeling_pe_audio_video import ( + PeAudioVideoContrastiveHead, + PeAudioVideoEncoder, + PeAudioVideoPreTrainedModel, +) +from .configuration_pe_audio import PeAudioConfig, PeAudioEncoderConfig + + +class PeAudioDacEncoderBlock(DacEncoderBlock): + def __init__(self, config: PreTrainedConfig, stride: int = 1, stride_index: int = 1): + super().__init__(config, stride=stride, stride_index=stride_index) + + +class PeAudioDacEncoder(DacEncoder): + def __init__(self, config: PreTrainedConfig): + super().__init__(config) + + +class PeAudioEncoderEmbedder(nn.Module): + def __init__(self, config: PeAudioEncoderConfig): + super().__init__() + self.dac_encoder = PeAudioDacEncoder(config.dac_config) + self.bottleneck = nn.Conv1d(config.dac_config.hidden_size, config.dac_config.codebook_dim, 1) + self.data_proj = nn.Linear(config.dac_config.codebook_dim, config.hidden_size) + self.config = config + + def forward( + self, + input_values: torch.Tensor, + padding_mask: torch.Tensor | None = None, + ) -> tuple[torch.Tensor, torch.Tensor | None]: + with torch.no_grad(), torch.backends.cudnn.flags(enabled=False): + hidden_states = self.dac_encoder(input_values) + hidden_states = self.bottleneck(hidden_states) + + codec_features = hidden_states.transpose(1, 2) + inputs_embeds = self.data_proj(codec_features) + + if padding_mask is not None: + padding_mask = padding_mask[:, :: self.config.dac_config.hop_length] + + return inputs_embeds, padding_mask + + +class PeAudioContrastiveHead(PeAudioVideoContrastiveHead): ... + + +class PeAudioPreTrainedModel(PeAudioVideoPreTrainedModel): + base_model_prefix = "audio_model" + + @torch.no_grad() + def _init_weights(self, module): + super()._init_weights(module) + if isinstance(module, nn.Conv1d): + init.trunc_normal_(module.weight, std=0.02) + init.constant_(module.bias, 0) + elif isinstance(module, Snake1d): + init.ones_(module.alpha) + elif isinstance(module, nn.ConvTranspose1d): + module.reset_parameters() + elif isinstance(module, nn.Embedding): + init.normal_(module.weight, mean=0.0, std=0.02) + + +@dataclass +@auto_docstring( + custom_intro=""" + Class for outputs of [`PeAudioEncoder`]. + """ +) +class PeAudioEncoderOutput(BaseModelOutputWithPooling): + codec_features: torch.FloatTensor | None = None + output_mask: tuple[torch.FloatTensor] | None = None + + +# TODO: add the capture of codec features? +@auto_docstring( + custom_intro=""" + The PeAudio Encoder model. + """ +) +class PeAudioEncoder(PeAudioVideoEncoder): + base_model_prefix = "audio_model.audio_encoder" + + @can_return_tuple + @merge_with_config_defaults + @capture_outputs + def forward( + self, + input_values: torch.Tensor, + padding_mask: torch.Tensor | None = None, + **kwargs, + ) -> tuple | BaseModelOutputWithPooling: + inputs_embeds, padding_mask = self.embedder(input_values, padding_mask=padding_mask) + inputs_embeds, attention_mask = self.patch_embedder(inputs_embeds, padding_mask=padding_mask) + + if attention_mask is not None: + attention_mask = create_bidirectional_mask( + config=self.config, + inputs_embeds=inputs_embeds, + attention_mask=attention_mask, + ) + + position_ids = torch.arange(inputs_embeds.shape[1], device=inputs_embeds.device).unsqueeze(0) + position_embeddings = self.rotary_emb(inputs_embeds, position_ids) + + hidden_states = inputs_embeds + for encoder_layer in self.layers[: self.config.num_hidden_layers]: + hidden_states = encoder_layer( + hidden_states, + attention_mask=attention_mask, + position_embeddings=position_embeddings, + **kwargs, + ) + + hidden_states = self.norm(hidden_states) + hidden_states = self.output(hidden_states) + + return PeAudioEncoderOutput( + last_hidden_state=hidden_states[:, 1:], + pooler_output=hidden_states[:, 0], + output_mask=padding_mask, + ) + + +# TODO: not sure about the typing for text_model_output +@dataclass +# @auto_docstring +class PeAudioOutput(ModelOutput): + loss: torch.FloatTensor | None = None + logits_audio_text: torch.FloatTensor | None = None + text_audio_embeds: torch.FloatTensor | None = None + audio_embeds: torch.FloatTensor | None = None + text_outputs: BaseModelOutputWithPooling = None + audio_outputs: BaseModelOutputWithPooling = None + + def to_tuple(self) -> tuple[Any]: + return tuple( + self[k] if k not in ["text_outputs", "audio_outputs"] else getattr(self, k).to_tuple() for k in self.keys() + ) + + +class PeAudioModel(PeAudioPreTrainedModel): + def __init__(self, config: PeAudioConfig): + super().__init__(config) + self.text_model = AutoModel.from_config(config.text_config) + self.audio_encoder = PeAudioEncoder(config.audio_config) + + self.text_audio_head = PeAudioContrastiveHead(config.text_config.hidden_size, config.text_config.hidden_size) + self.audio_head = PeAudioContrastiveHead(config.audio_config.hidden_size, config.text_config.hidden_size) + + self.text_audio_logit_scale = nn.Parameter(torch.zeros(1)) + self.text_audio_logit_bias = nn.Parameter(torch.zeros(1)) + + self.post_init() + + def get_text_audio_embeds(self, input_ids, attention_mask=None): + # TODO: naming can be improved here... + text_outputs: MaskedLMOutput = self.text_model( + input_ids=input_ids, + attention_mask=attention_mask, + return_dict=True, + ) + text_audio_embeds = text_outputs.hidden_states[-1][:, 0] + return self.text_audio_head(text_audio_embeds) + + def get_audio_embeds(self, input_values, padding_mask=None): + audio_outputs: BaseModelOutputWithPooling = self.audio_encoder( + input_values=input_values, + padding_mask=padding_mask, + return_dict=True, + ) + audio_embeds = audio_outputs.pooler_output + return self.audio_head(audio_embeds) + + @can_return_tuple + def forward( + self, + input_ids: torch.Tensor, + input_values: torch.Tensor, + attention_mask: torch.Tensor | None = None, + padding_mask: torch.Tensor | None = None, + return_loss: bool | None = None, + **kwargs, + ) -> PeAudioOutput: + audio_outputs: BaseModelOutputWithPooling = self.audio_encoder( + input_values=input_values, padding_mask=padding_mask, **kwargs + ) + + kwargs["output_hidden_states"] = True + text_outputs: MaskedLMOutput = self.text_model(input_ids=input_ids, attention_mask=attention_mask, **kwargs) + + audio_embeds = audio_outputs.pooler_output + audio_embeds = self.audio_head(audio_embeds) + + text_audio_embeds = text_outputs.hidden_states[-1][:, 0] + text_audio_embeds = self.text_audio_head(text_audio_embeds) + + logits_audio_text = audio_embeds @ text_audio_embeds.T + logits_audio_text = logits_audio_text * self.text_audio_logit_scale.to( + logits_audio_text.device + ) + self.text_audio_logit_bias.to(logits_audio_text.device) + + loss = None + if return_loss: + labels = torch.eye(logits_audio_text.shape[0], device=logits_audio_text.device) + loss = -F.logsigmoid(labels * logits_audio_text).sum() / logits_audio_text.shape[0] + + return PeAudioOutput( + logits_audio_text=logits_audio_text, + text_audio_embeds=text_audio_embeds, + audio_embeds=audio_embeds, + text_outputs=text_outputs, + audio_outputs=audio_outputs, + loss=loss, + ) + + +# TODO: underline in documentation that logits output shape is +# 1. Model: (n_audio, n_text) +# 2. Frame-level: (n_audio, n_text, n_frames) +class PeAudioFrameLevelModel(PeAudioModel): + def get_audio_embeds(self, input_values, padding_mask=None): + audio_outputs: BaseModelOutputWithPooling = self.audio_encoder( + input_values=input_values, + padding_mask=padding_mask, + return_dict=True, + ) + audio_embeds = audio_outputs.last_hidden_state + audio_embeds = self.audio_head(audio_embeds) + return audio_embeds + + @can_return_tuple + def forward( + self, + input_ids: torch.Tensor, + input_values: torch.Tensor, + attention_mask: torch.Tensor | None = None, + padding_mask: torch.Tensor | None = None, + return_loss: bool | None = None, + **kwargs, + ) -> PeAudioOutput: + audio_outputs: BaseModelOutputWithPooling = self.audio_encoder( + input_values=input_values, padding_mask=padding_mask, **kwargs + ) + kwargs["output_hidden_states"] = True + text_outputs: MaskedLMOutput = self.text_model(input_ids=input_ids, attention_mask=attention_mask, **kwargs) + + audio_embeds = audio_outputs.last_hidden_state + audio_embeds = self.audio_head(audio_embeds) + + text_audio_embeds = text_outputs.hidden_states[-1][:, 0] + text_audio_embeds = self.text_audio_head(text_audio_embeds) + + logits_audio_text = (audio_embeds @ text_audio_embeds.T).transpose(1, 2) + logits_audio_text = logits_audio_text * self.text_audio_logit_scale + self.text_audio_logit_bias + + loss = None + if return_loss: + labels = torch.eye(logits_audio_text.shape[0], device=logits_audio_text.device) + loss = -F.logsigmoid(labels * logits_audio_text).sum() / logits_audio_text.shape[0] + + return PeAudioOutput( + logits_audio_text=logits_audio_text, + text_audio_embeds=text_audio_embeds, + audio_embeds=audio_embeds, + text_outputs=text_outputs, + audio_outputs=audio_outputs, + loss=loss, + ) + + +__all__ = [ + "PeAudioFrameLevelModel", + "PeAudioModel", + "PeAudioEncoder", +] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pe_audio/processing_pe_audio.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pe_audio/processing_pe_audio.py new file mode 100644 index 0000000000000000000000000000000000000000..f12c462aa9bcb487b8f8205673a0f4c5083ce656 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pe_audio/processing_pe_audio.py @@ -0,0 +1,23 @@ +# Copyright 2025 the HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from ...processing_utils import ProcessorMixin + + +class PeAudioProcessor(ProcessorMixin): + attributes = ["feature_extractor", "tokenizer"] + feature_extractor_class = "PeAudioFeatureExtractor" + tokenizer_class = "AutoTokenizer" + + +__all__ = ["PeAudioProcessor"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pe_audio_video/__init__.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pe_audio_video/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..c8f0b6d9565d457606de3e5bfa9b7c378c13cb70 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pe_audio_video/__init__.py @@ -0,0 +1,28 @@ +# Copyright 2025 the HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from typing import TYPE_CHECKING + +from ...utils import _LazyModule +from ...utils.import_utils import define_import_structure + + +if TYPE_CHECKING: + from .configuration_pe_audio_video import * + from .modeling_pe_audio_video import * + from .processing_pe_audio_video import * +else: + import sys + + _file = globals()["__file__"] + sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__) diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pe_audio_video/configuration_pe_audio_video.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pe_audio_video/configuration_pe_audio_video.py new file mode 100644 index 0000000000000000000000000000000000000000..0aeae40b3613ade369d4315c81d708010ef7b011 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pe_audio_video/configuration_pe_audio_video.py @@ -0,0 +1,223 @@ +# Copyright 2025 the HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + + +from ...configuration_utils import PreTrainedConfig, PretrainedConfig +from ...modeling_rope_utils import RopeParameters +from ...utils import logging +from ..auto import CONFIG_MAPPING, AutoConfig + + +logger = logging.get_logger(__name__) + + +class PeAudioVideoEncoderConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`PeAudioVideoEncoderModel`]. It is used to instantiate a + PeAudioVideoEncoder model according to the specified arguments, defining the model architecture. Instantiating a configuration + with the defaults will yield a similar configuration to that of pe-av-large. + e.g. [facebook/pe-av-large](https://huggingface.co/facebook/pe-av-large) + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + + Args: + audio_config (`Union[PreTrainedConfig, dict]`, *optional*): + Configuration for the audio encoder. If a dictionary is provided, it is used to instantiate + [`~transformers.PeAudioEncoderConfig`]. + video_config (`Union[PreTrainedConfig, dict]`, *optional*): + Configuration for the video encoder. If a dictionary is provided, it is used to instantiate + [`~transformers.PeVideoEncoderConfig`]. + hidden_size (`int`, *optional*, defaults to 1792): + Dimension of the hidden representations. + intermediate_size (`int`, *optional*, defaults to 4800): + Dimension of the feedforward layers in the Transformer blocks. + num_hidden_layers (`int`, *optional*, defaults to 6): + Number of Transformer encoder blocks. + num_attention_heads (`int`, *optional*, defaults to 14): + Number of attention heads used in each attention layer. + num_key_value_heads (`int`, *optional*): + Number of key and value heads for grouped-query attention. If unset, this defaults to `num_attention_heads`. + head_dim (`int`, *optional*, defaults to 128): + Dimension of each attention head for query, key, and value projections. + hidden_act (`str`, *optional*, defaults to `"silu"`): + The non-linear activation function (function or string) in the Transformer blocks. + max_position_embeddings (`int`, *optional*, defaults to 10000): + Maximum sequence length supported by the rotary position embeddings. + initializer_range (`float`, *optional*, defaults to 0.02): + Standard deviation of the truncated normal initializer for weight matrices. + rms_norm_eps (`float`, *optional*, defaults to 1e-05): + Epsilon used by the RMS normalization layers. + rope_parameters (`Union[RopeParameters, dict]`, *optional*, defaults to `{'rope_theta': 20000}`): + Parameters for the rotary position embeddings, such as the base `rope_theta`. + attention_bias (`bool`, *optional*, defaults to `False`): + Whether to use bias terms in the query, key, value, and output projections. + attention_dropout (`float`, *optional*, defaults to 0.0): + Dropout ratio applied to attention probabilities. + + ```python + >>> from transformers import PeAudioVideoEncoder, PeAudioVideoEncoderConfig + + >>> # Initializing a PeAudioVideoEncoder style configuration + >>> configuration = PeAudioVideoEncoderConfig() + + >>> # Initializing a model from the pe-av-large style configuration + >>> model = PeAudioVideoEncoder(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "pe_audio_video_encoder" + base_config_key = "audio_video_config" + sub_configs = {"audio_config": AutoConfig, "video_config": AutoConfig} + + def __init__( + self, + audio_config: dict | PreTrainedConfig | None = None, + video_config: dict | PreTrainedConfig | None = None, + hidden_size: int | None = 1792, + intermediate_size: int | None = 4800, + num_hidden_layers: int | None = 6, + num_attention_heads: int | None = 14, + num_key_value_heads: int | None = None, + head_dim: int | None = 128, + hidden_act: str | None = "silu", + max_position_embeddings: int | None = 10000, + initializer_range: float | None = 0.02, + rms_norm_eps: float | None = 1e-5, + rope_parameters: RopeParameters | dict | None = {"rope_theta": 20000}, + attention_bias: bool | None = False, + attention_dropout: float | None = 0.0, + **kwargs, + ): + self.hidden_size = hidden_size + self.intermediate_size = intermediate_size + self.num_hidden_layers = num_hidden_layers + self.num_attention_heads = num_attention_heads + + # for backward compatibility + if num_key_value_heads is None: + num_key_value_heads = num_attention_heads + + self.num_key_value_heads = num_key_value_heads + self.head_dim = head_dim + self.hidden_act = hidden_act + self.max_position_embeddings = max_position_embeddings + self.initializer_range = initializer_range + self.rms_norm_eps = rms_norm_eps + self.rope_parameters = rope_parameters + self.attention_bias = attention_bias + self.attention_dropout = attention_dropout + + if isinstance(audio_config, dict): + audio_config["model_type"] = audio_config.get("model_type", "pe_audio_encoder") + audio_config = CONFIG_MAPPING[audio_config["model_type"]](**audio_config) + elif audio_config is None: + audio_config = CONFIG_MAPPING["pe_audio_encoder"]() + + if isinstance(video_config, dict): + video_config["model_type"] = video_config.get("model_type", "pe_video_encoder") + video_config = CONFIG_MAPPING[video_config["model_type"]](**video_config) + elif video_config is None: + video_config = CONFIG_MAPPING["pe_video_encoder"]() + + self.audio_config = audio_config + self.video_config = video_config + + super().__init__(**kwargs) + + +class PeAudioVideoConfig(PretrainedConfig): + r""" + This is the configuration class to store the configuration of a [`PeAudioVideoModel`]. It is used to instantiate a + PeAudioVideoModel model according to the specified arguments, defining the model architecture. Instantiating a configuration + with the defaults will yield a similar configuration to that of pe-av-large. + e.g. [facebook/pe-av-large](https://huggingface.co/facebook/pe-av-large) + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + + Args: + text_config (`dict` or `PreTrainedConfig`, *optional*): + Configuration for the text model component. + audio_video_config (`dict` or `PreTrainedConfig`, *optional*): + Configuration for the audio-video encoder component. + + ```python + >>> from transformers import PeAudioVideoModel, PeAudioVideoConfig + + >>> # Initializing a PeAudioVideoModel style configuration + >>> configuration = PeAudioVideoConfig() + + >>> # Initializing a model from the pe-av-large style configuration + >>> model = PeAudioModel(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "pe_audio_video" + sub_configs = {"text_config": AutoConfig, "audio_video_config": PeAudioVideoEncoderConfig} + + _default_text_config_kwargs = { + "model_type": "modernbert", + "hidden_size": 1024, + "intermediate_size": 2624, + "num_hidden_layers": 22, + "num_attention_heads": 16, + } + + def __init__( + self, + text_config=None, + audio_video_config=None, + **kwargs, + ): + if isinstance(text_config, dict): + text_config["model_type"] = text_config.get("model_type", "modernbert") + text_config = CONFIG_MAPPING[text_config["model_type"]]( + **{**self._default_text_config_kwargs, **text_config} + ) + elif text_config is None: + text_config = CONFIG_MAPPING["modernbert"](**self._default_text_config_kwargs) + + if isinstance(audio_video_config, dict): + audio_video_config = PeAudioVideoEncoderConfig(**audio_video_config) + elif audio_video_config is None: + audio_video_config = PeAudioVideoEncoderConfig() + + self.text_config = text_config + self.audio_video_config = audio_video_config + + super().__init__(**kwargs) + + @property + def audio_config(self): + return CONFIG_MAPPING["pe_audio"]( + text_config=self.text_config, + audio_config=self.audio_video_config.audio_config, + ) + + @property + def video_config(self): + return CONFIG_MAPPING["pe_video"]( + text_config=self.text_config, + video_config=self.audio_video_config.video_config, + ) + + +__all__ = ["PeAudioVideoEncoderConfig", "PeAudioVideoConfig"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pe_audio_video/modeling_pe_audio_video.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pe_audio_video/modeling_pe_audio_video.py new file mode 100644 index 0000000000000000000000000000000000000000..a76e1b40f27c3cdcf034b81a7038388e06802ea5 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pe_audio_video/modeling_pe_audio_video.py @@ -0,0 +1,978 @@ +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# This file was automatically generated from src/transformers/models/pe_audio_video/modular_pe_audio_video.py. +# Do NOT edit this file manually as any edits will be overwritten by the generation of +# the file from the modular. If any change should be done, please apply the change to the +# modular_pe_audio_video.py file directly. One of our CI enforces this. +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# Copyright 2025 the HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from collections.abc import Callable +from dataclasses import dataclass +from typing import Any, Optional + +import torch +import torch.nn as nn + +from ... import initialization as init +from ...activations import ACT2FN +from ...cache_utils import Cache +from ...integrations import use_kernel_forward_from_hub, use_kernelized_func +from ...masking_utils import create_bidirectional_mask +from ...modeling_layers import GradientCheckpointingLayer +from ...modeling_outputs import BaseModelOutputWithPooling, MaskedLMOutput +from ...modeling_rope_utils import ROPE_INIT_FUNCTIONS, dynamic_rope_update +from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel +from ...processing_utils import Unpack +from ...utils import ModelOutput, TransformersKwargs, auto_docstring, can_return_tuple +from ...utils.generic import maybe_autocast, merge_with_config_defaults +from ...utils.output_capturing import capture_outputs +from ..auto import AutoModel +from .configuration_pe_audio_video import PeAudioVideoConfig, PeAudioVideoEncoderConfig + + +class PeAudioVideoMaskedGroupNorm(nn.GroupNorm): + def forward(self, x, padding_mask=None): + if padding_mask is None: + return super().forward(x) + + batch_size, hidden_size, seq_len = x.shape + group_size = hidden_size // self.num_groups + grouped_shape = (batch_size, -1, group_size, seq_len) + + x_grouped = x.view(grouped_shape) + padding_mask_grouped = padding_mask.reshape(grouped_shape).bool() + + mean = torch.masked.mean(x_grouped, mask=padding_mask_grouped, dim=(2, 3), keepdim=True) + var = torch.masked.var(x_grouped, mask=padding_mask_grouped, dim=(2, 3), keepdim=True, unbiased=False) + + x_norm = (x_grouped - mean) / torch.sqrt(var + self.eps) + x_norm = x_norm.view(x.shape) + + if self.affine: + x_norm = x_norm * self.weight.view(1, -1, 1) + self.bias.view(1, -1, 1) + + return x_norm * padding_mask + + +class PeAudioVideoConvBlock1d(nn.Module): + def __init__(self, config): + super().__init__() + self.groupnorm = PeAudioVideoMaskedGroupNorm(num_groups=1, num_channels=config.hidden_size) + self.activation = nn.SiLU() + self.project = nn.Conv1d( + in_channels=config.hidden_size, + out_channels=config.hidden_size, + kernel_size=3, + padding="same", + ) + + def forward(self, x, padding_mask=None): + x = self.groupnorm(x, padding_mask=padding_mask) + x = self.activation(x) + return self.project(x) + + +class PeAudioVideoResnetBlock1d(nn.Module): + def __init__(self, config): + super().__init__() + self.block1 = PeAudioVideoConvBlock1d(config) + self.block2 = PeAudioVideoConvBlock1d(config) + + def forward(self, hidden_states, padding_mask=None): + """ + Args: + hidden_states: (batch_size, seq_len, hidden_size) + padding_mask: (batch_size, seq_len) + Returns: + hidden_states: (batch_size, seq_len, hidden_size) + """ + # transpose for convolutions + # (batch_size, seq_len, hidden_size) -> (batch_size, hidden_size, seq_len) + hidden_states = hidden_states.transpose(1, 2) + + if padding_mask is not None: + padding_mask = padding_mask.unsqueeze(1).expand_as(hidden_states) + + residual = hidden_states + hidden_states = self.block1(hidden_states, padding_mask=padding_mask) + hidden_states = self.block2(hidden_states, padding_mask=padding_mask) + hidden_states = residual + hidden_states + + return hidden_states.transpose(1, 2) + + +class PeAudioVideoEncoderPatchEmbedder(nn.Module): + def __init__(self, config): + super().__init__() + self.resnet_block = PeAudioVideoResnetBlock1d(config) + self.class_embedding = nn.Parameter(torch.randn(1, 1, config.hidden_size)) + + def forward(self, inputs_embeds, padding_mask=None): + # Embedding step: prepend class token and run the ResNet block. + hidden_states = torch.cat( + [self.class_embedding.expand(inputs_embeds.size(0), -1, -1), inputs_embeds], + dim=1, + ) + + if padding_mask is not None: + # TODO: any reason why we take padding_mask[0] and not just 1? + padding_mask = torch.cat([padding_mask[:, [0]], padding_mask], dim=1) + + hidden_states = self.resnet_block(hidden_states, padding_mask=padding_mask) + return hidden_states, padding_mask + + +class PeAudioVideoContrastiveHead(nn.Module): + def __init__( + self, + in_dim: int, + out_dim: int, + ) -> None: + super().__init__() + self.layer_norm = nn.LayerNorm(normalized_shape=in_dim, eps=1e-6) + self.proj = nn.Linear(in_dim, out_dim, bias=False) + + def forward(self, x: torch.Tensor) -> torch.FloatTensor: + return self.proj(self.layer_norm(x)) + + +class PeAudioVideoEncoderEmbedder(nn.Module): + def __init__(self, config: PeAudioVideoEncoderConfig): + super().__init__() + self.audio_encoder = AutoModel.from_config(config.audio_config) + self.video_encoder = AutoModel.from_config(config.video_config) + + self.video_proj = nn.Conv1d(config.video_config.hidden_size, config.audio_config.hidden_size, 1) + self.video_norm = nn.LayerNorm(config.audio_config.hidden_size) + + self.concat_modality_proj = nn.Linear( + config.audio_config.hidden_size + config.video_config.hidden_size, + config.hidden_size, + ) + self.data_proj = nn.Linear(config.hidden_size, config.hidden_size) + + def _align_video_hidden_state( + self, + video_hidden_state: torch.Tensor, + audio_hidden_state: torch.Tensor, + padding_mask_videos: torch.Tensor | None = None, + padding_mask: torch.Tensor | None = None, + ) -> torch.Tensor: + """ + Align video_hidden_state to audio_hidden_state by nearest neighbor interpolation. + """ + if video_hidden_state.shape[1] == audio_hidden_state.shape[1]: + return video_hidden_state + + if padding_mask_videos is not None: + video_lengths = padding_mask_videos.sum(dim=-1) + else: + video_lengths = video_hidden_state.shape[1] * video_hidden_state.new_ones( + video_hidden_state.shape[0], dtype=torch.long + ) + + if padding_mask is not None: + audio_lengths = padding_mask.sum(dim=-1) + else: + audio_lengths = audio_hidden_state.shape[1] * audio_hidden_state.new_ones( + audio_hidden_state.shape[0], dtype=torch.long + ) + + if (audio_lengths == video_hidden_state.shape[1]).all() or ( + video_lengths == audio_hidden_state.shape[1] + ).all(): + # no need to align taking into account the padding masks + # note: when one of the above is true, we can expect the other to be true as there is no reason + # to have masked audio without masked video and vice versa + + return nn.functional.interpolate( + video_hidden_state.transpose(1, 2), size=audio_hidden_state.shape[1], mode="nearest" + ).transpose(1, 2) + + aligned_shape = (*audio_hidden_state.shape[:2], video_hidden_state.shape[-1]) + aligned_hidden_state = audio_hidden_state.new_zeros(aligned_shape) + + for i, (hidden_state, video_length, audio_length) in enumerate( + zip(video_hidden_state, video_lengths, audio_lengths) + ): + hidden_state = hidden_state[:video_length] + if hidden_state.numel() > 0 and audio_length > 0: + interpolated_hidden_state = nn.functional.interpolate( + hidden_state[None].transpose(1, 2), size=audio_length, mode="nearest" + ).transpose(1, 2)[0] + aligned_hidden_state[i, :audio_length, :] = interpolated_hidden_state + + return aligned_hidden_state + + def forward( + self, + input_values: torch.Tensor, + pixel_values_videos: torch.Tensor, + padding_mask: torch.Tensor | None = None, + padding_mask_videos: torch.Tensor | None = None, + ): + audio_output = self.audio_encoder(input_values, padding_mask=padding_mask) + video_output = self.video_encoder(pixel_values_videos, padding_mask_videos=padding_mask_videos) + + audio_hidden_state = audio_output.last_hidden_state + video_hidden_state = video_output.last_hidden_state + padding_mask = audio_output.output_mask + + video_hidden_state = self.video_proj(video_hidden_state.transpose(1, 2)).transpose(1, 2) + video_hidden_state = self._align_video_hidden_state( + video_hidden_state=video_hidden_state, + audio_hidden_state=audio_hidden_state, + padding_mask_videos=padding_mask_videos, + padding_mask=padding_mask, + ) + video_hidden_state = self.video_norm(video_hidden_state) + inputs_embeds = torch.cat([audio_hidden_state, video_hidden_state], dim=-1) + inputs_embeds = self.concat_modality_proj(inputs_embeds) + inputs_embeds = self.data_proj(inputs_embeds) + + return inputs_embeds, padding_mask, audio_output, video_output + + +def repeat_kv(hidden_states: torch.Tensor, n_rep: int) -> torch.Tensor: + """ + This is the equivalent of torch.repeat_interleave(x, dim=1, repeats=n_rep). The hidden states go from (batch, + num_key_value_heads, seqlen, head_dim) to (batch, num_attention_heads, seqlen, head_dim) + """ + batch, num_key_value_heads, slen, head_dim = hidden_states.shape + if n_rep == 1: + return hidden_states + hidden_states = hidden_states[:, :, None, :, :].expand(batch, num_key_value_heads, n_rep, slen, head_dim) + return hidden_states.reshape(batch, num_key_value_heads * n_rep, slen, head_dim) + + +def eager_attention_forward( + module: nn.Module, + query: torch.Tensor, + key: torch.Tensor, + value: torch.Tensor, + attention_mask: torch.Tensor | None, + scaling: float, + dropout: float = 0.0, + **kwargs: Unpack[TransformersKwargs], +): + key_states = repeat_kv(key, module.num_key_value_groups) + value_states = repeat_kv(value, module.num_key_value_groups) + + attn_weights = torch.matmul(query, key_states.transpose(2, 3)) * scaling + if attention_mask is not None: + attn_weights = attn_weights + attention_mask + + attn_weights = nn.functional.softmax(attn_weights, dim=-1, dtype=torch.float32).to(query.dtype) + attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training) + attn_output = torch.matmul(attn_weights, value_states) + attn_output = attn_output.transpose(1, 2).contiguous() + + return attn_output, attn_weights + + +def stack_freqs(cos: torch.Tensor, sin: torch.Tensor): + dim = cos.size(-1) + cos = cos.narrow(-1, 0, dim // 2) + sin = sin.narrow(-1, 0, dim // 2) + freqs_cis = torch.stack((cos, -sin, sin, cos), dim=-1).view(*cos.size(), 2, 2) + return freqs_cis + + +def apply_rotary_pos_emb(q, k, cos, sin, unsqueeze_dim=1): + freqs_cis = stack_freqs(cos, sin) + freqs_cis = freqs_cis.unsqueeze(unsqueeze_dim) + q_ = q.reshape(*q.shape[:-1], -1, 1, 2) + k_ = k.reshape(*k.shape[:-1], -1, 1, 2) + return (q_ * freqs_cis).sum(5).flatten(3), (k_ * freqs_cis).sum(5).flatten(3) + + +@use_kernelized_func(apply_rotary_pos_emb) +class PeAudioVideoEncoderAttention(nn.Module): + """Multi-headed attention from 'Attention Is All You Need' paper""" + + def __init__(self, config, layer_idx): + super().__init__() + self.layer_type = config.layer_types[layer_idx] if hasattr(config, "layer_types") else None + self.config = config + self.layer_idx = layer_idx + self.head_dim = getattr(config, "head_dim", config.hidden_size // config.num_attention_heads) + self.num_key_value_groups = config.num_attention_heads // config.num_key_value_heads + self.scaling = self.head_dim**-0.5 + self.attention_dropout = config.attention_dropout + self.is_causal = False + + self.q_proj = nn.Linear( + config.hidden_size, config.num_attention_heads * self.head_dim, bias=config.attention_bias + ) + self.k_proj = nn.Linear( + config.hidden_size, config.num_key_value_heads * self.head_dim, bias=config.attention_bias + ) + self.v_proj = nn.Linear( + config.hidden_size, config.num_key_value_heads * self.head_dim, bias=config.attention_bias + ) + self.o_proj = nn.Linear( + config.num_attention_heads * self.head_dim, config.hidden_size, bias=config.attention_bias + ) + self.q_norm = PeAudioVideoEncoderRMSNorm( + self.head_dim, eps=config.rms_norm_eps + ) # unlike olmo, only on the head dim! + self.k_norm = PeAudioVideoEncoderRMSNorm( + self.head_dim, eps=config.rms_norm_eps + ) # thus post q_norm does not need reshape + + def forward( + self, + hidden_states: torch.Tensor, + position_embeddings: tuple[torch.Tensor, torch.Tensor] | None = None, + attention_mask: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor, torch.Tensor]: + input_shape = hidden_states.shape[:-1] + hidden_shape = (*input_shape, -1, self.head_dim) + + query_states = self.q_norm(self.q_proj(hidden_states).view(hidden_shape)).transpose(1, 2) + key_states = self.k_norm(self.k_proj(hidden_states).view(hidden_shape)).transpose(1, 2) + value_states = self.v_proj(hidden_states).view(hidden_shape).transpose(1, 2) + + cos, sin = position_embeddings + query_states, key_states = apply_rotary_pos_emb(query_states, key_states, cos, sin) + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, eager_attention_forward + ) + + attn_output, attn_weights = attention_interface( + self, + query_states, + key_states, + value_states, + attention_mask, + dropout=0.0 if not self.training else self.attention_dropout, + scaling=self.scaling, + **kwargs, + ) + + attn_output = attn_output.reshape(*input_shape, -1).contiguous() + attn_output = self.o_proj(attn_output) + return attn_output, attn_weights + + +class PeAudioVideoEncoderMLP(nn.Module): + def __init__(self, config): + super().__init__() + self.config = config + self.hidden_size = config.hidden_size + self.intermediate_size = config.intermediate_size + self.gate_proj = nn.Linear(self.hidden_size, self.intermediate_size, bias=False) + self.up_proj = nn.Linear(self.hidden_size, self.intermediate_size, bias=False) + self.down_proj = nn.Linear(self.intermediate_size, self.hidden_size, bias=False) + self.act_fn = ACT2FN[config.hidden_act] + + def forward(self, x): + down_proj = self.down_proj(self.act_fn(self.gate_proj(x)) * self.up_proj(x)) + return down_proj + + +class PeAudioVideoEncoderLayer(GradientCheckpointingLayer): + def __init__(self, config, layer_idx): + super().__init__() + self.hidden_size = config.hidden_size + + self.self_attn = PeAudioVideoEncoderAttention(config=config, layer_idx=layer_idx) + + self.mlp = PeAudioVideoEncoderMLP(config) + self.input_layernorm = PeAudioVideoEncoderRMSNorm(config.hidden_size, eps=config.rms_norm_eps) + self.post_attention_layernorm = PeAudioVideoEncoderRMSNorm(config.hidden_size, eps=config.rms_norm_eps) + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.Tensor | None = None, + position_ids: torch.LongTensor | None = None, + past_key_values: Cache | None = None, + use_cache: bool | None = False, + cache_position: torch.LongTensor | None = None, + position_embeddings: tuple[torch.Tensor, torch.Tensor] | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> torch.Tensor: + residual = hidden_states + hidden_states = self.input_layernorm(hidden_states) + # Self Attention + hidden_states, _ = self.self_attn( + hidden_states=hidden_states, + attention_mask=attention_mask, + position_ids=position_ids, + past_key_values=past_key_values, + use_cache=use_cache, + cache_position=cache_position, + position_embeddings=position_embeddings, + **kwargs, + ) + hidden_states = residual + hidden_states + + # Fully Connected + residual = hidden_states + hidden_states = self.post_attention_layernorm(hidden_states) + hidden_states = self.mlp(hidden_states) + hidden_states = residual + hidden_states + return hidden_states + + +@use_kernel_forward_from_hub("RMSNorm") +class PeAudioVideoEncoderRMSNorm(nn.Module): + def __init__(self, hidden_size, eps: float = 1e-6) -> None: + """ + PeAudioVideoEncoderRMSNorm is equivalent to T5LayerNorm + """ + super().__init__() + self.weight = nn.Parameter(torch.ones(hidden_size)) + self.variance_epsilon = eps + + def forward(self, hidden_states: torch.Tensor) -> torch.Tensor: + input_dtype = hidden_states.dtype + hidden_states = hidden_states.to(torch.float32) + variance = hidden_states.pow(2).mean(-1, keepdim=True) + hidden_states = hidden_states * torch.rsqrt(variance + self.variance_epsilon) + return self.weight * hidden_states.to(input_dtype) + + def extra_repr(self): + return f"{tuple(self.weight.shape)}, eps={self.variance_epsilon}" + + +class PeAudioVideoEncoderRotaryEmbedding(nn.Module): + inv_freq: torch.Tensor # fix linting for `register_buffer` + + def __init__(self, config: PeAudioVideoEncoderConfig, device=None): + super().__init__() + self.max_seq_len_cached = config.max_position_embeddings + self.original_max_seq_len = config.max_position_embeddings + + self.config = config + + self.rope_type = self.config.rope_parameters["rope_type"] + rope_init_fn: Callable = self.compute_default_rope_parameters + if self.rope_type != "default": + rope_init_fn = ROPE_INIT_FUNCTIONS[self.rope_type] + inv_freq, self.attention_scaling = rope_init_fn(self.config, device) + + self.register_buffer("inv_freq", inv_freq, persistent=False) + self.register_buffer("original_inv_freq", inv_freq.clone(), persistent=False) + + @staticmethod + def compute_default_rope_parameters( + config: PeAudioVideoEncoderConfig | None = None, + device: Optional["torch.device"] = None, + seq_len: int | None = None, + ) -> tuple["torch.Tensor", float]: + """ + Computes the inverse frequencies according to the original RoPE implementation + Args: + config ([`~transformers.PreTrainedConfig`]): + The model configuration. + device (`torch.device`): + The device to use for initialization of the inverse frequencies. + seq_len (`int`, *optional*): + The current sequence length. Unused for this type of RoPE. + Returns: + Tuple of (`torch.Tensor`, `float`), containing the inverse frequencies for the RoPE embeddings and the + post-processing scaling factor applied to the computed cos/sin (unused in this type of RoPE). + """ + base = config.rope_parameters["rope_theta"] + dim = getattr(config, "head_dim", None) or config.hidden_size // config.num_attention_heads + + attention_factor = 1.0 # Unused in this type of RoPE + + # Compute the inverse frequencies + inv_freq = 1.0 / ( + base ** (torch.arange(0, dim, 2, dtype=torch.int64).to(device=device, dtype=torch.float) / dim) + ) + return inv_freq, attention_factor + + @torch.no_grad() + @dynamic_rope_update # power user: used with advanced RoPE types (e.g. dynamic rope) + def forward(self, x, position_ids): + inv_freq_expanded = self.inv_freq[None, :, None].float().expand(position_ids.shape[0], -1, 1).to(x.device) + position_ids_expanded = position_ids[:, None, :].float() + + device_type = x.device.type if isinstance(x.device.type, str) and x.device.type != "mps" else "cpu" + with maybe_autocast(device_type=device_type, enabled=False): # Force float32 + freqs = (inv_freq_expanded.float() @ position_ids_expanded.float()).transpose(1, 2) + emb = torch.cat((freqs, freqs), dim=-1) + cos = emb.cos() * self.attention_scaling + sin = emb.sin() * self.attention_scaling + + return cos.to(dtype=x.dtype), sin.to(dtype=x.dtype) + + +@auto_docstring +class PeAudioVideoPreTrainedModel(PreTrainedModel): + config: PeAudioVideoConfig + base_model_prefix = "model" + supports_gradient_checkpointing = True + _no_split_modules = ["PeAudioVideoEncoderLayer"] + _skip_keys_device_placement = ["past_key_values"] + _supports_flash_attn = True + _supports_sdpa = True + _supports_flex_attn = True + + _can_compile_fullgraph = True + _supports_attention_backend = True + _can_record_outputs = { + "hidden_states": PeAudioVideoEncoderLayer, + "attentions": PeAudioVideoEncoderAttention, + } + + def _init_weights(self, module): + super()._init_weights(module) + + if hasattr(self.config, "initializer_range"): + std = self.config.initializer_range + else: + # 0.02 is the standard default value across the library + std = getattr(self.config.get_text_config(), "initializer_range", 0.02) + + if isinstance(module, PeAudioVideoEncoderPatchEmbedder): + embed_dim = module.class_embedding.shape[-1] + init.normal_(module.class_embedding, mean=0.0, std=embed_dim**-0.5 * std) + + +@dataclass +@auto_docstring( + custom_intro=""" + Class for outputs of [`PeAudioVideoEncoder`]. + """ +) +class PeAudioVideoEncoderOutput(BaseModelOutputWithPooling): + audio_model_output: BaseModelOutputWithPooling | None = None + video_model_output: BaseModelOutputWithPooling | None = None + + +@auto_docstring( + custom_intro=""" + The PeAudioVideo Encoder model. + """ +) +class PeAudioVideoEncoder(PeAudioVideoPreTrainedModel): + config: PeAudioVideoEncoderConfig + main_input_name = "input_values" + base_model_prefix = "audio_video_encoder" + + def __init__(self, config: PeAudioVideoEncoderConfig): + super().__init__(config) + self.embedder = PeAudioVideoEncoderEmbedder(config) + self.patch_embedder = PeAudioVideoEncoderPatchEmbedder(config) + self.layers = nn.ModuleList( + [PeAudioVideoEncoderLayer(config, layer_idx) for layer_idx in range(config.num_hidden_layers)] + ) + self.norm = PeAudioVideoEncoderRMSNorm(config.hidden_size, eps=config.rms_norm_eps) + self.rotary_emb = PeAudioVideoEncoderRotaryEmbedding(config=config) + self.output = nn.Linear(config.hidden_size, config.hidden_size, bias=False) + self.gradient_checkpointing = False + + self.post_init() + + @can_return_tuple + @merge_with_config_defaults + @capture_outputs + def forward( + self, + input_values: torch.Tensor | None = None, + pixel_values_videos: torch.Tensor | None = None, + padding_mask: torch.Tensor | None = None, + padding_mask_videos: torch.Tensor | None = None, + **kwargs, + ) -> tuple | PeAudioVideoEncoderOutput: + inputs_embeds, padding_mask, audio_output, video_output = self.embedder( + input_values, + pixel_values_videos, + padding_mask=padding_mask, + padding_mask_videos=padding_mask_videos, + ) + inputs_embeds, attention_mask = self.patch_embedder(inputs_embeds, padding_mask=padding_mask) + + if attention_mask is not None: + attention_mask = create_bidirectional_mask( + config=self.config, + inputs_embeds=inputs_embeds, + attention_mask=attention_mask, + ) + + position_ids = torch.arange(inputs_embeds.shape[1], device=inputs_embeds.device).unsqueeze(0) + position_embeddings = self.rotary_emb(inputs_embeds, position_ids) + + hidden_states = inputs_embeds + for encoder_layer in self.layers[: self.config.num_hidden_layers]: + hidden_states = encoder_layer( + hidden_states, + attention_mask=attention_mask, + position_embeddings=position_embeddings, + **kwargs, + ) + + hidden_states = self.norm(hidden_states) + hidden_states = self.output(hidden_states) + + return PeAudioVideoEncoderOutput( + last_hidden_state=hidden_states[:, 1:], + pooler_output=hidden_states[:, 0], + audio_model_output=audio_output, + video_model_output=video_output, + ) + + +@dataclass +@auto_docstring( + custom_intro=""" + Class for outputs of [`PeAudioVideoModel`] when using text, audio, and/or video. + """ +) +class PeAudioVideoOutput(ModelOutput): + # embeddings + audio_embeds: torch.FloatTensor | None = None + video_embeds: torch.FloatTensor | None = None + audio_video_embeds: torch.FloatTensor | None = None + text_audio_embeds: torch.FloatTensor | None = None + text_video_embeds: torch.FloatTensor | None = None + text_audio_video_embeds: torch.FloatTensor | None = None + audio_plus_text_embeds: torch.FloatTensor | None = None + video_plus_text_embeds: torch.FloatTensor | None = None + + # model outputs + # TODO: update types to the correct ones + text_outputs: MaskedLMOutput | None = None + audio_outputs: BaseModelOutputWithPooling | None = None + video_outputs: BaseModelOutputWithPooling | None = None + audio_video_outputs: BaseModelOutputWithPooling | None = None + + # logits + logits_audio_text: torch.FloatTensor | None = None + logits_video_text: torch.FloatTensor | None = None + logits_audio_video: torch.FloatTensor | None = None + logits_audio_video_text: torch.FloatTensor | None = None + logits_audio_plus_text_video: torch.FloatTensor | None = None + logits_video_plus_text_audio: torch.FloatTensor | None = None + + audio_text_loss: torch.FloatTensor | None = None + video_text_loss: torch.FloatTensor | None = None + audio_video_loss: torch.FloatTensor | None = None + audio_video_text_loss: torch.FloatTensor | None = None + audio_plus_text_video_loss: torch.FloatTensor | None = None + video_plus_text_audio_loss: torch.FloatTensor | None = None + loss: torch.FloatTensor | None = None + + def to_tuple(self) -> tuple[Any]: + return tuple(self[k] if not k.endswith("model_output") else getattr(self, k).to_tuple() for k in self.keys()) + + +@dataclass +class AudioVideoEmbeddings(ModelOutput): + audio_embeds: torch.FloatTensor | None = None + video_embeds: torch.FloatTensor | None = None + audio_video_embeds: torch.FloatTensor | None = None + + +class PeAudioVideoModel(PeAudioVideoPreTrainedModel): + _tied_weights_keys = { + r"audio_model\.text_model\.(?!rotary_emb)": r"^text_model\.(?!rotary_emb)", + r"video_model\.text_model\.(?!rotary_emb)": r"^text_model\.(?!rotary_emb)", + r"audio_video_encoder\.embedder\.audio_encoder\.(?!rotary_emb)": r"audio_model\.audio_encoder\.(?!rotary_emb)", + r"audio_video_encoder\.embedder\.video_encoder\.(?!rotary_emb|.*\.rope\.pos_embed)": r"video_model\.video_encoder\.(?!rotary_emb|.*\.rope\.pos_embed)", + } + + def __init__(self, config: PeAudioVideoConfig): + super().__init__(config) + self.text_model = AutoModel.from_config(config.text_config) + self.audio_model = AutoModel.from_config(config.audio_config) + self.video_model = AutoModel.from_config(config.video_config) + self.audio_video_encoder = PeAudioVideoEncoder(config.audio_video_config) + + text_hidden_size = config.text_config.hidden_size + audio_hidden_size = config.audio_video_config.audio_config.hidden_size + video_hidden_size = config.audio_video_config.video_config.hidden_size + + # audio-video + self.audio_video_head = PeAudioVideoContrastiveHead(config.audio_video_config.hidden_size, text_hidden_size) + self.text_audio_video_head = PeAudioVideoContrastiveHead(text_hidden_size, text_hidden_size) + self.audio_video_logit_scale = nn.Parameter(torch.zeros(1)) + self.audio_video_logit_bias = nn.Parameter(torch.zeros(1)) + self.text_audio_video_logit_scale = nn.Parameter(torch.zeros(1)) + self.text_audio_video_logit_bias = nn.Parameter(torch.zeros(1)) + + # text-audio + self.audio_plus_text_head = PeAudioVideoContrastiveHead(text_hidden_size + audio_hidden_size, text_hidden_size) + self.audio_plus_text_logit_scale = nn.Parameter(torch.zeros(1)) + self.audio_plus_text_logit_bias = nn.Parameter(torch.zeros(1)) + + # text-video + self.video_plus_text_head = PeAudioVideoContrastiveHead(text_hidden_size + video_hidden_size, text_hidden_size) + self.video_plus_text_logit_scale = nn.Parameter(torch.zeros(1)) + self.video_plus_text_logit_bias = nn.Parameter(torch.zeros(1)) + + self.post_init() + + def _contrastive_loss(self, logits: torch.Tensor) -> torch.Tensor: + labels = torch.eye(logits.shape[0], device=logits.device) + loss = -nn.functional.logsigmoid(labels * logits).sum() / logits.shape[0] + return loss + + def get_text_audio_embeds(self, input_ids, attention_mask=None): + return self.audio_model.get_text_embeds(input_ids, attention_mask) + + def get_text_video_embeds(self, input_ids, attention_mask=None): + return self.video_model.get_text_embeds(input_ids, attention_mask) + + def get_text_audio_video_embeds(self, input_ids, attention_mask=None): + text_outputs: MaskedLMOutput = self.text_model( + input_ids=input_ids, + attention_mask=attention_mask, + return_dict=True, + ) + text_embeds = text_outputs.hidden_states[-1][:, 0] + return self.text_audio_video_head(text_embeds) + + def get_audio_embeds(self, input_values, padding_mask=None): + return self.audio_model.get_audio_embeds(input_values, padding_mask) + + def get_video_embeds(self, pixel_values_videos, padding_mask_videos=None): + return self.video_model.get_video_embeds(pixel_values_videos, padding_mask_videos) + + def get_audio_video_embeds( + self, + input_values: torch.Tensor, + pixel_values_videos: torch.Tensor, + padding_mask: torch.Tensor | None = None, + padding_mask_videos: torch.Tensor | None = None, + return_audio_embeds: bool = False, + return_video_embeds: bool = False, + **kwargs, + ) -> AudioVideoEmbeddings: + audio_video_outputs = self.audio_video_encoder( + input_values=input_values, + pixel_values_videos=pixel_values_videos, + padding_mask=padding_mask, + padding_mask_videos=padding_mask_videos, + **kwargs, + ) + if return_audio_embeds: + audio_embeds = self.audio_model.audio_head(audio_video_outputs.audio_model_output.pooler_output) + if return_video_embeds: + video_embeds = self.video_model.video_head(audio_video_outputs.video_model_output.pooler_output) + + audio_video_embeds = self.audio_video_head(audio_video_outputs.pooler_output) + return AudioVideoEmbeddings( + audio_embeds=audio_embeds if return_audio_embeds else None, + video_embeds=video_embeds if return_video_embeds else None, + audio_video_embeds=audio_video_embeds, + ) + + def get_audio_plus_text_embeds( + self, + input_ids: torch.Tensor, + input_values: torch.Tensor, + attention_mask: torch.Tensor | None = None, + padding_mask: torch.Tensor | None = None, + ) -> torch.Tensor: + audio_embeds = self.audio_model.audio_encoder( + input_values=input_values, + padding_mask=padding_mask, + return_dict=True, + ) + text_outputs: MaskedLMOutput = self.text_model( + input_ids=input_ids, + attention_mask=attention_mask, + return_dict=True, + ) + text_embeds = text_outputs.hidden_states[-1][:, 0] + + audio_plus_text_embeds = torch.cat([text_embeds, audio_embeds], dim=-1) + return self.audio_plus_text_head(audio_plus_text_embeds) + + def get_video_plus_text_embeds( + self, + input_ids: torch.Tensor, + pixel_values_videos: torch.Tensor, + attention_mask: torch.Tensor | None = None, + padding_mask_videos: torch.Tensor | None = None, + ) -> torch.Tensor: + video_embeds = self.video_model.video_encoder( + pixel_values_videos=pixel_values_videos, + padding_mask_videos=padding_mask_videos, + return_dict=True, + ) + text_outputs: MaskedLMOutput = self.text_model( + input_ids=input_ids, + attention_mask=attention_mask, + return_dict=True, + ) + text_embeds = text_outputs.hidden_states[-1][:, 0] + + video_plus_text_embeds = torch.cat([text_embeds, video_embeds], dim=-1) + return self.video_plus_text_head(video_plus_text_embeds) + + @can_return_tuple + def forward( + self, + input_ids: torch.Tensor | None = None, + pixel_values_videos: torch.Tensor | None = None, + input_values: torch.Tensor | None = None, + attention_mask: torch.Tensor | None = None, + padding_mask_videos: torch.Tensor | None = None, + padding_mask: torch.Tensor | None = None, + return_loss=False, + **kwargs, + ) -> PeAudioVideoOutput: + if sum([input_ids is not None, pixel_values_videos is not None, input_values is not None]) < 2: + raise ValueError("At least two of input_ids, pixel_values_videos, or input_values must be provided") + + if pixel_values_videos is None: + outputs = self.audio_model( + input_ids=input_ids, + input_values=input_values, + attention_mask=attention_mask, + padding_mask=padding_mask, + return_dict=True, + ) + audio_plus_text_embeds = torch.cat( + [outputs.audio_outputs.pooler_output, outputs.text_outputs.hidden_states[-1][:, 0]], dim=-1 + ) + audio_plus_text_embeds = self.audio_plus_text_head(audio_plus_text_embeds) + return PeAudioVideoOutput(audio_plus_text_embeds=audio_plus_text_embeds, **outputs) + + if input_values is None: + outputs = self.video_model( + input_ids=input_ids, + pixel_values_videos=pixel_values_videos, + attention_mask=attention_mask, + padding_mask_videos=padding_mask_videos, + return_dict=True, + ) + video_plus_text_embeds = torch.cat( + [outputs.video_outputs.pooler_output, outputs.text_outputs.hidden_states[-1][:, 0]], dim=-1 + ) + video_plus_text_embeds = self.video_plus_text_head(video_plus_text_embeds) + return PeAudioVideoOutput(video_plus_text_embeds=video_plus_text_embeds, **outputs) + + audio_video_outputs = self.audio_video_encoder( + input_values=input_values, + pixel_values_videos=pixel_values_videos, + padding_mask=padding_mask, + padding_mask_videos=padding_mask_videos, + **kwargs, + ) + audio_embeds = audio_video_outputs.audio_model_output.pooler_output + video_embeds = audio_video_outputs.video_model_output.pooler_output + audio_video_embeds = audio_video_outputs.pooler_output + + audio_embeds = self.audio_model.audio_head(audio_embeds) + video_embeds = self.video_model.video_head(video_embeds) + audio_video_embeds = self.audio_video_head(audio_video_embeds) + logits_audio_video = audio_embeds @ video_embeds.T + logits_audio_video = logits_audio_video * self.audio_video_logit_scale + self.audio_video_logit_bias + audio_video_loss = self._contrastive_loss(logits_audio_video) if return_loss else None + + if input_ids is None: + return PeAudioVideoOutput( + logits_audio_video=logits_audio_video, + audio_embeds=audio_embeds, + video_embeds=video_embeds, + audio_video_embeds=audio_video_embeds, + loss=audio_video_loss, + audio_video_loss=audio_video_loss, + ) + + kwargs["output_hidden_states"] = True + text_outputs = self.text_model(input_ids=input_ids, attention_mask=attention_mask, **kwargs) + text_embeds = text_outputs.hidden_states[-1][:, 0] + audio_plus_text_embeds = torch.cat([audio_video_outputs.audio_model_output.pooler_output, text_embeds], dim=-1) + video_plus_text_embeds = torch.cat([audio_video_outputs.video_model_output.pooler_output, text_embeds], dim=-1) + + text_audio_embeds = self.audio_model.text_audio_head(text_embeds) + text_video_embeds = self.video_model.text_video_head(text_embeds) + text_audio_video_embeds = self.text_audio_video_head(text_embeds) + audio_plus_text_embeds = self.audio_plus_text_head(audio_plus_text_embeds) + video_plus_text_embeds = self.video_plus_text_head(video_plus_text_embeds) + + logits_audio_text = audio_embeds @ text_audio_embeds.T + logits_video_text = video_embeds @ text_video_embeds.T + logits_audio_video_text = audio_video_embeds @ text_audio_video_embeds.T + + logits_audio_plus_text_video = audio_plus_text_embeds @ video_embeds.T + logits_video_plus_text_audio = video_plus_text_embeds @ audio_embeds.T + + logits_audio_text = ( + logits_audio_text * self.audio_model.text_audio_logit_scale + self.audio_model.text_audio_logit_bias + ) + logits_video_text = ( + logits_video_text * self.video_model.text_video_logit_scale + self.video_model.text_video_logit_bias + ) + logits_audio_video_text = ( + logits_audio_video_text * self.text_audio_video_logit_scale + self.text_audio_video_logit_bias + ) + + logits_audio_plus_text_video = ( + logits_audio_plus_text_video * self.audio_plus_text_logit_scale + self.audio_plus_text_logit_bias + ) + logits_video_plus_text_audio = ( + logits_video_plus_text_audio * self.video_plus_text_logit_scale + self.video_plus_text_logit_bias + ) + + if return_loss: + audio_text_loss = self._contrastive_loss(logits_audio_text) + video_text_loss = self._contrastive_loss(logits_video_text) + audio_video_text_loss = self._contrastive_loss(logits_audio_video_text) + audio_plus_text_video_loss = self._contrastive_loss(logits_audio_plus_text_video) + video_plus_text_audio_loss = self._contrastive_loss(logits_video_plus_text_audio) + loss = ( + audio_video_text_loss + + audio_text_loss + + video_text_loss + + audio_video_loss + + audio_plus_text_video_loss + + video_plus_text_audio_loss + ) + + return PeAudioVideoOutput( + # embeddings + audio_embeds=audio_embeds, + video_embeds=video_embeds, + audio_video_embeds=audio_video_embeds, + text_audio_embeds=text_audio_embeds, + text_video_embeds=text_video_embeds, + text_audio_video_embeds=text_audio_video_embeds, + audio_plus_text_embeds=audio_plus_text_embeds, + video_plus_text_embeds=video_plus_text_embeds, + # model outputs + text_outputs=text_outputs, + audio_outputs=audio_video_outputs.audio_model_output, + video_outputs=audio_video_outputs.video_model_output, + audio_video_outputs=audio_video_outputs, + # logits + logits_audio_text=logits_audio_text, + logits_video_text=logits_video_text, + logits_audio_video=logits_audio_video, + logits_audio_video_text=logits_audio_video_text, + logits_audio_plus_text_video=logits_audio_plus_text_video, + logits_video_plus_text_audio=logits_video_plus_text_audio, + # losses + audio_text_loss=audio_text_loss if return_loss else None, + video_text_loss=video_text_loss if return_loss else None, + audio_video_loss=audio_video_loss if return_loss else None, + audio_video_text_loss=audio_video_text_loss if return_loss else None, + audio_plus_text_video_loss=audio_plus_text_video_loss if return_loss else None, + video_plus_text_audio_loss=video_plus_text_audio_loss if return_loss else None, + loss=loss if return_loss else None, + ) + + +__all__ = ["PeAudioVideoModel", "PeAudioVideoEncoder"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pe_audio_video/modular_pe_audio_video.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pe_audio_video/modular_pe_audio_video.py new file mode 100644 index 0000000000000000000000000000000000000000..c8d603a3e6ebd1b83d781ef3dd2462e89131ec8e --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pe_audio_video/modular_pe_audio_video.py @@ -0,0 +1,771 @@ +# Copyright 2025 the HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from collections.abc import Callable +from dataclasses import dataclass +from typing import Any + +import torch +import torch.nn as nn + +from ... import initialization as init +from ...masking_utils import create_bidirectional_mask +from ...modeling_outputs import BaseModelOutputWithPooling, MaskedLMOutput +from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel, eager_attention_forward +from ...processing_utils import Unpack +from ...utils import ModelOutput, TransformersKwargs, auto_docstring, can_return_tuple +from ...utils.generic import merge_with_config_defaults +from ...utils.output_capturing import capture_outputs +from ..auto import AutoModel +from ..qwen3.modeling_qwen3 import Qwen3Attention, Qwen3DecoderLayer, Qwen3RMSNorm, Qwen3RotaryEmbedding +from .configuration_pe_audio_video import PeAudioVideoConfig, PeAudioVideoEncoderConfig + + +class PeAudioVideoMaskedGroupNorm(nn.GroupNorm): + def forward(self, x, padding_mask=None): + if padding_mask is None: + return super().forward(x) + + batch_size, hidden_size, seq_len = x.shape + group_size = hidden_size // self.num_groups + grouped_shape = (batch_size, -1, group_size, seq_len) + + x_grouped = x.view(grouped_shape) + padding_mask_grouped = padding_mask.reshape(grouped_shape).bool() + + mean = torch.masked.mean(x_grouped, mask=padding_mask_grouped, dim=(2, 3), keepdim=True) + var = torch.masked.var(x_grouped, mask=padding_mask_grouped, dim=(2, 3), keepdim=True, unbiased=False) + + x_norm = (x_grouped - mean) / torch.sqrt(var + self.eps) + x_norm = x_norm.view(x.shape) + + if self.affine: + x_norm = x_norm * self.weight.view(1, -1, 1) + self.bias.view(1, -1, 1) + + return x_norm * padding_mask + + +class PeAudioVideoConvBlock1d(nn.Module): + def __init__(self, config): + super().__init__() + self.groupnorm = PeAudioVideoMaskedGroupNorm(num_groups=1, num_channels=config.hidden_size) + self.activation = nn.SiLU() + self.project = nn.Conv1d( + in_channels=config.hidden_size, + out_channels=config.hidden_size, + kernel_size=3, + padding="same", + ) + + def forward(self, x, padding_mask=None): + x = self.groupnorm(x, padding_mask=padding_mask) + x = self.activation(x) + return self.project(x) + + +class PeAudioVideoResnetBlock1d(nn.Module): + def __init__(self, config): + super().__init__() + self.block1 = PeAudioVideoConvBlock1d(config) + self.block2 = PeAudioVideoConvBlock1d(config) + + def forward(self, hidden_states, padding_mask=None): + """ + Args: + hidden_states: (batch_size, seq_len, hidden_size) + padding_mask: (batch_size, seq_len) + Returns: + hidden_states: (batch_size, seq_len, hidden_size) + """ + # transpose for convolutions + # (batch_size, seq_len, hidden_size) -> (batch_size, hidden_size, seq_len) + hidden_states = hidden_states.transpose(1, 2) + + if padding_mask is not None: + padding_mask = padding_mask.unsqueeze(1).expand_as(hidden_states) + + residual = hidden_states + hidden_states = self.block1(hidden_states, padding_mask=padding_mask) + hidden_states = self.block2(hidden_states, padding_mask=padding_mask) + hidden_states = residual + hidden_states + + return hidden_states.transpose(1, 2) + + +class PeAudioVideoEncoderPatchEmbedder(nn.Module): + def __init__(self, config): + super().__init__() + self.resnet_block = PeAudioVideoResnetBlock1d(config) + self.class_embedding = nn.Parameter(torch.randn(1, 1, config.hidden_size)) + + def forward(self, inputs_embeds, padding_mask=None): + # Embedding step: prepend class token and run the ResNet block. + hidden_states = torch.cat( + [self.class_embedding.expand(inputs_embeds.size(0), -1, -1), inputs_embeds], + dim=1, + ) + + if padding_mask is not None: + # TODO: any reason why we take padding_mask[0] and not just 1? + padding_mask = torch.cat([padding_mask[:, [0]], padding_mask], dim=1) + + hidden_states = self.resnet_block(hidden_states, padding_mask=padding_mask) + return hidden_states, padding_mask + + +class PeAudioVideoContrastiveHead(nn.Module): + def __init__( + self, + in_dim: int, + out_dim: int, + ) -> None: + super().__init__() + self.layer_norm = nn.LayerNorm(normalized_shape=in_dim, eps=1e-6) + self.proj = nn.Linear(in_dim, out_dim, bias=False) + + def forward(self, x: torch.Tensor) -> torch.FloatTensor: + return self.proj(self.layer_norm(x)) + + +class PeAudioVideoEncoderEmbedder(nn.Module): + def __init__(self, config: PeAudioVideoEncoderConfig): + super().__init__() + self.audio_encoder = AutoModel.from_config(config.audio_config) + self.video_encoder = AutoModel.from_config(config.video_config) + + self.video_proj = nn.Conv1d(config.video_config.hidden_size, config.audio_config.hidden_size, 1) + self.video_norm = nn.LayerNorm(config.audio_config.hidden_size) + + self.concat_modality_proj = nn.Linear( + config.audio_config.hidden_size + config.video_config.hidden_size, + config.hidden_size, + ) + self.data_proj = nn.Linear(config.hidden_size, config.hidden_size) + + def _align_video_hidden_state( + self, + video_hidden_state: torch.Tensor, + audio_hidden_state: torch.Tensor, + padding_mask_videos: torch.Tensor | None = None, + padding_mask: torch.Tensor | None = None, + ) -> torch.Tensor: + """ + Align video_hidden_state to audio_hidden_state by nearest neighbor interpolation. + """ + if video_hidden_state.shape[1] == audio_hidden_state.shape[1]: + return video_hidden_state + + if padding_mask_videos is not None: + video_lengths = padding_mask_videos.sum(dim=-1) + else: + video_lengths = video_hidden_state.shape[1] * video_hidden_state.new_ones( + video_hidden_state.shape[0], dtype=torch.long + ) + + if padding_mask is not None: + audio_lengths = padding_mask.sum(dim=-1) + else: + audio_lengths = audio_hidden_state.shape[1] * audio_hidden_state.new_ones( + audio_hidden_state.shape[0], dtype=torch.long + ) + + if (audio_lengths == video_hidden_state.shape[1]).all() or ( + video_lengths == audio_hidden_state.shape[1] + ).all(): + # no need to align taking into account the padding masks + # note: when one of the above is true, we can expect the other to be true as there is no reason + # to have masked audio without masked video and vice versa + + return nn.functional.interpolate( + video_hidden_state.transpose(1, 2), size=audio_hidden_state.shape[1], mode="nearest" + ).transpose(1, 2) + + aligned_shape = (*audio_hidden_state.shape[:2], video_hidden_state.shape[-1]) + aligned_hidden_state = audio_hidden_state.new_zeros(aligned_shape) + + for i, (hidden_state, video_length, audio_length) in enumerate( + zip(video_hidden_state, video_lengths, audio_lengths) + ): + hidden_state = hidden_state[:video_length] + if hidden_state.numel() > 0 and audio_length > 0: + interpolated_hidden_state = nn.functional.interpolate( + hidden_state[None].transpose(1, 2), size=audio_length, mode="nearest" + ).transpose(1, 2)[0] + aligned_hidden_state[i, :audio_length, :] = interpolated_hidden_state + + return aligned_hidden_state + + def forward( + self, + input_values: torch.Tensor, + pixel_values_videos: torch.Tensor, + padding_mask: torch.Tensor | None = None, + padding_mask_videos: torch.Tensor | None = None, + ): + audio_output = self.audio_encoder(input_values, padding_mask=padding_mask) + video_output = self.video_encoder(pixel_values_videos, padding_mask_videos=padding_mask_videos) + + audio_hidden_state = audio_output.last_hidden_state + video_hidden_state = video_output.last_hidden_state + padding_mask = audio_output.output_mask + + video_hidden_state = self.video_proj(video_hidden_state.transpose(1, 2)).transpose(1, 2) + video_hidden_state = self._align_video_hidden_state( + video_hidden_state=video_hidden_state, + audio_hidden_state=audio_hidden_state, + padding_mask_videos=padding_mask_videos, + padding_mask=padding_mask, + ) + video_hidden_state = self.video_norm(video_hidden_state) + inputs_embeds = torch.cat([audio_hidden_state, video_hidden_state], dim=-1) + inputs_embeds = self.concat_modality_proj(inputs_embeds) + inputs_embeds = self.data_proj(inputs_embeds) + + return inputs_embeds, padding_mask, audio_output, video_output + + +class PeAudioVideoEncoderAttention(Qwen3Attention): + def __init__(self, config, layer_idx): + super().__init__(config, layer_idx) + self.is_causal = False + del self.sliding_window + + def forward( + self, + hidden_states: torch.Tensor, + position_embeddings: tuple[torch.Tensor, torch.Tensor] | None = None, + attention_mask: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor, torch.Tensor]: + input_shape = hidden_states.shape[:-1] + hidden_shape = (*input_shape, -1, self.head_dim) + + query_states = self.q_norm(self.q_proj(hidden_states).view(hidden_shape)).transpose(1, 2) + key_states = self.k_norm(self.k_proj(hidden_states).view(hidden_shape)).transpose(1, 2) + value_states = self.v_proj(hidden_states).view(hidden_shape).transpose(1, 2) + + cos, sin = position_embeddings + query_states, key_states = apply_rotary_pos_emb(query_states, key_states, cos, sin) + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, eager_attention_forward + ) + + attn_output, attn_weights = attention_interface( + self, + query_states, + key_states, + value_states, + attention_mask, + dropout=0.0 if not self.training else self.attention_dropout, + scaling=self.scaling, + **kwargs, + ) + + attn_output = attn_output.reshape(*input_shape, -1).contiguous() + attn_output = self.o_proj(attn_output) + return attn_output, attn_weights + + +class PeAudioVideoEncoderLayer(Qwen3DecoderLayer): + def __init__(self, config, layer_idx): + super().__init__(config, layer_idx) + del self.attention_type + + +class PeAudioVideoEncoderRMSNorm(Qwen3RMSNorm): ... + + +def stack_freqs(cos: torch.Tensor, sin: torch.Tensor): + dim = cos.size(-1) + cos = cos.narrow(-1, 0, dim // 2) + sin = sin.narrow(-1, 0, dim // 2) + freqs_cis = torch.stack((cos, -sin, sin, cos), dim=-1).view(*cos.size(), 2, 2) + return freqs_cis + + +def apply_rotary_pos_emb(q, k, cos, sin, unsqueeze_dim=1): + freqs_cis = stack_freqs(cos, sin) + freqs_cis = freqs_cis.unsqueeze(unsqueeze_dim) + q_ = q.reshape(*q.shape[:-1], -1, 1, 2) + k_ = k.reshape(*k.shape[:-1], -1, 1, 2) + return (q_ * freqs_cis).sum(5).flatten(3), (k_ * freqs_cis).sum(5).flatten(3) + + +class PeAudioVideoEncoderRotaryEmbedding(Qwen3RotaryEmbedding): ... + + +@auto_docstring +class PeAudioVideoPreTrainedModel(PreTrainedModel): + config: PeAudioVideoConfig + base_model_prefix = "model" + supports_gradient_checkpointing = True + _no_split_modules = ["PeAudioVideoEncoderLayer"] + _skip_keys_device_placement = ["past_key_values"] + _supports_flash_attn = True + _supports_sdpa = True + _supports_flex_attn = True + + _can_compile_fullgraph = True + _supports_attention_backend = True + _can_record_outputs = { + "hidden_states": PeAudioVideoEncoderLayer, + "attentions": PeAudioVideoEncoderAttention, + } + + def _init_weights(self, module): + super()._init_weights(module) + + if hasattr(self.config, "initializer_range"): + std = self.config.initializer_range + else: + # 0.02 is the standard default value across the library + std = getattr(self.config.get_text_config(), "initializer_range", 0.02) + + if isinstance(module, PeAudioVideoEncoderPatchEmbedder): + embed_dim = module.class_embedding.shape[-1] + init.normal_(module.class_embedding, mean=0.0, std=embed_dim**-0.5 * std) + + +@dataclass +@auto_docstring( + custom_intro=""" + Class for outputs of [`PeAudioVideoEncoder`]. + """ +) +class PeAudioVideoEncoderOutput(BaseModelOutputWithPooling): + audio_model_output: BaseModelOutputWithPooling | None = None + video_model_output: BaseModelOutputWithPooling | None = None + + +@auto_docstring( + custom_intro=""" + The PeAudioVideo Encoder model. + """ +) +class PeAudioVideoEncoder(PeAudioVideoPreTrainedModel): + config: PeAudioVideoEncoderConfig + main_input_name = "input_values" + base_model_prefix = "audio_video_encoder" + + def __init__(self, config: PeAudioVideoEncoderConfig): + super().__init__(config) + self.embedder = PeAudioVideoEncoderEmbedder(config) + self.patch_embedder = PeAudioVideoEncoderPatchEmbedder(config) + self.layers = nn.ModuleList( + [PeAudioVideoEncoderLayer(config, layer_idx) for layer_idx in range(config.num_hidden_layers)] + ) + self.norm = PeAudioVideoEncoderRMSNorm(config.hidden_size, eps=config.rms_norm_eps) + self.rotary_emb = PeAudioVideoEncoderRotaryEmbedding(config=config) + self.output = nn.Linear(config.hidden_size, config.hidden_size, bias=False) + self.gradient_checkpointing = False + + self.post_init() + + @can_return_tuple + @merge_with_config_defaults + @capture_outputs + def forward( + self, + input_values: torch.Tensor | None = None, + pixel_values_videos: torch.Tensor | None = None, + padding_mask: torch.Tensor | None = None, + padding_mask_videos: torch.Tensor | None = None, + **kwargs, + ) -> tuple | PeAudioVideoEncoderOutput: + inputs_embeds, padding_mask, audio_output, video_output = self.embedder( + input_values, + pixel_values_videos, + padding_mask=padding_mask, + padding_mask_videos=padding_mask_videos, + ) + inputs_embeds, attention_mask = self.patch_embedder(inputs_embeds, padding_mask=padding_mask) + + if attention_mask is not None: + attention_mask = create_bidirectional_mask( + config=self.config, + inputs_embeds=inputs_embeds, + attention_mask=attention_mask, + ) + + position_ids = torch.arange(inputs_embeds.shape[1], device=inputs_embeds.device).unsqueeze(0) + position_embeddings = self.rotary_emb(inputs_embeds, position_ids) + + hidden_states = inputs_embeds + for encoder_layer in self.layers[: self.config.num_hidden_layers]: + hidden_states = encoder_layer( + hidden_states, + attention_mask=attention_mask, + position_embeddings=position_embeddings, + **kwargs, + ) + + hidden_states = self.norm(hidden_states) + hidden_states = self.output(hidden_states) + + return PeAudioVideoEncoderOutput( + last_hidden_state=hidden_states[:, 1:], + pooler_output=hidden_states[:, 0], + audio_model_output=audio_output, + video_model_output=video_output, + ) + + +@dataclass +@auto_docstring( + custom_intro=""" + Class for outputs of [`PeAudioVideoModel`] when using text, audio, and/or video. + """ +) +class PeAudioVideoOutput(ModelOutput): + # embeddings + audio_embeds: torch.FloatTensor | None = None + video_embeds: torch.FloatTensor | None = None + audio_video_embeds: torch.FloatTensor | None = None + text_audio_embeds: torch.FloatTensor | None = None + text_video_embeds: torch.FloatTensor | None = None + text_audio_video_embeds: torch.FloatTensor | None = None + audio_plus_text_embeds: torch.FloatTensor | None = None + video_plus_text_embeds: torch.FloatTensor | None = None + + # model outputs + # TODO: update types to the correct ones + text_outputs: MaskedLMOutput | None = None + audio_outputs: BaseModelOutputWithPooling | None = None + video_outputs: BaseModelOutputWithPooling | None = None + audio_video_outputs: BaseModelOutputWithPooling | None = None + + # logits + logits_audio_text: torch.FloatTensor | None = None + logits_video_text: torch.FloatTensor | None = None + logits_audio_video: torch.FloatTensor | None = None + logits_audio_video_text: torch.FloatTensor | None = None + logits_audio_plus_text_video: torch.FloatTensor | None = None + logits_video_plus_text_audio: torch.FloatTensor | None = None + + audio_text_loss: torch.FloatTensor | None = None + video_text_loss: torch.FloatTensor | None = None + audio_video_loss: torch.FloatTensor | None = None + audio_video_text_loss: torch.FloatTensor | None = None + audio_plus_text_video_loss: torch.FloatTensor | None = None + video_plus_text_audio_loss: torch.FloatTensor | None = None + loss: torch.FloatTensor | None = None + + def to_tuple(self) -> tuple[Any]: + return tuple(self[k] if not k.endswith("model_output") else getattr(self, k).to_tuple() for k in self.keys()) + + +@dataclass +class AudioVideoEmbeddings(ModelOutput): + audio_embeds: torch.FloatTensor | None = None + video_embeds: torch.FloatTensor | None = None + audio_video_embeds: torch.FloatTensor | None = None + + +class PeAudioVideoModel(PeAudioVideoPreTrainedModel): + _tied_weights_keys = { + r"audio_model\.text_model\.(?!rotary_emb)": r"^text_model\.(?!rotary_emb)", + r"video_model\.text_model\.(?!rotary_emb)": r"^text_model\.(?!rotary_emb)", + r"audio_video_encoder\.embedder\.audio_encoder\.(?!rotary_emb)": r"audio_model\.audio_encoder\.(?!rotary_emb)", + r"audio_video_encoder\.embedder\.video_encoder\.(?!rotary_emb|.*\.rope\.pos_embed)": r"video_model\.video_encoder\.(?!rotary_emb|.*\.rope\.pos_embed)", + } + + def __init__(self, config: PeAudioVideoConfig): + super().__init__(config) + self.text_model = AutoModel.from_config(config.text_config) + self.audio_model = AutoModel.from_config(config.audio_config) + self.video_model = AutoModel.from_config(config.video_config) + self.audio_video_encoder = PeAudioVideoEncoder(config.audio_video_config) + + text_hidden_size = config.text_config.hidden_size + audio_hidden_size = config.audio_video_config.audio_config.hidden_size + video_hidden_size = config.audio_video_config.video_config.hidden_size + + # audio-video + self.audio_video_head = PeAudioVideoContrastiveHead(config.audio_video_config.hidden_size, text_hidden_size) + self.text_audio_video_head = PeAudioVideoContrastiveHead(text_hidden_size, text_hidden_size) + self.audio_video_logit_scale = nn.Parameter(torch.zeros(1)) + self.audio_video_logit_bias = nn.Parameter(torch.zeros(1)) + self.text_audio_video_logit_scale = nn.Parameter(torch.zeros(1)) + self.text_audio_video_logit_bias = nn.Parameter(torch.zeros(1)) + + # text-audio + self.audio_plus_text_head = PeAudioVideoContrastiveHead(text_hidden_size + audio_hidden_size, text_hidden_size) + self.audio_plus_text_logit_scale = nn.Parameter(torch.zeros(1)) + self.audio_plus_text_logit_bias = nn.Parameter(torch.zeros(1)) + + # text-video + self.video_plus_text_head = PeAudioVideoContrastiveHead(text_hidden_size + video_hidden_size, text_hidden_size) + self.video_plus_text_logit_scale = nn.Parameter(torch.zeros(1)) + self.video_plus_text_logit_bias = nn.Parameter(torch.zeros(1)) + + self.post_init() + + def _contrastive_loss(self, logits: torch.Tensor) -> torch.Tensor: + labels = torch.eye(logits.shape[0], device=logits.device) + loss = -nn.functional.logsigmoid(labels * logits).sum() / logits.shape[0] + return loss + + def get_text_audio_embeds(self, input_ids, attention_mask=None): + return self.audio_model.get_text_embeds(input_ids, attention_mask) + + def get_text_video_embeds(self, input_ids, attention_mask=None): + return self.video_model.get_text_embeds(input_ids, attention_mask) + + def get_text_audio_video_embeds(self, input_ids, attention_mask=None): + text_outputs: MaskedLMOutput = self.text_model( + input_ids=input_ids, + attention_mask=attention_mask, + return_dict=True, + ) + text_embeds = text_outputs.hidden_states[-1][:, 0] + return self.text_audio_video_head(text_embeds) + + def get_audio_embeds(self, input_values, padding_mask=None): + return self.audio_model.get_audio_embeds(input_values, padding_mask) + + def get_video_embeds(self, pixel_values_videos, padding_mask_videos=None): + return self.video_model.get_video_embeds(pixel_values_videos, padding_mask_videos) + + def get_audio_video_embeds( + self, + input_values: torch.Tensor, + pixel_values_videos: torch.Tensor, + padding_mask: torch.Tensor | None = None, + padding_mask_videos: torch.Tensor | None = None, + return_audio_embeds: bool = False, + return_video_embeds: bool = False, + **kwargs, + ) -> AudioVideoEmbeddings: + audio_video_outputs = self.audio_video_encoder( + input_values=input_values, + pixel_values_videos=pixel_values_videos, + padding_mask=padding_mask, + padding_mask_videos=padding_mask_videos, + **kwargs, + ) + if return_audio_embeds: + audio_embeds = self.audio_model.audio_head(audio_video_outputs.audio_model_output.pooler_output) + if return_video_embeds: + video_embeds = self.video_model.video_head(audio_video_outputs.video_model_output.pooler_output) + + audio_video_embeds = self.audio_video_head(audio_video_outputs.pooler_output) + return AudioVideoEmbeddings( + audio_embeds=audio_embeds if return_audio_embeds else None, + video_embeds=video_embeds if return_video_embeds else None, + audio_video_embeds=audio_video_embeds, + ) + + def get_audio_plus_text_embeds( + self, + input_ids: torch.Tensor, + input_values: torch.Tensor, + attention_mask: torch.Tensor | None = None, + padding_mask: torch.Tensor | None = None, + ) -> torch.Tensor: + audio_embeds = self.audio_model.audio_encoder( + input_values=input_values, + padding_mask=padding_mask, + return_dict=True, + ) + text_outputs: MaskedLMOutput = self.text_model( + input_ids=input_ids, + attention_mask=attention_mask, + return_dict=True, + ) + text_embeds = text_outputs.hidden_states[-1][:, 0] + + audio_plus_text_embeds = torch.cat([text_embeds, audio_embeds], dim=-1) + return self.audio_plus_text_head(audio_plus_text_embeds) + + def get_video_plus_text_embeds( + self, + input_ids: torch.Tensor, + pixel_values_videos: torch.Tensor, + attention_mask: torch.Tensor | None = None, + padding_mask_videos: torch.Tensor | None = None, + ) -> torch.Tensor: + video_embeds = self.video_model.video_encoder( + pixel_values_videos=pixel_values_videos, + padding_mask_videos=padding_mask_videos, + return_dict=True, + ) + text_outputs: MaskedLMOutput = self.text_model( + input_ids=input_ids, + attention_mask=attention_mask, + return_dict=True, + ) + text_embeds = text_outputs.hidden_states[-1][:, 0] + + video_plus_text_embeds = torch.cat([text_embeds, video_embeds], dim=-1) + return self.video_plus_text_head(video_plus_text_embeds) + + @can_return_tuple + def forward( + self, + input_ids: torch.Tensor | None = None, + pixel_values_videos: torch.Tensor | None = None, + input_values: torch.Tensor | None = None, + attention_mask: torch.Tensor | None = None, + padding_mask_videos: torch.Tensor | None = None, + padding_mask: torch.Tensor | None = None, + return_loss=False, + **kwargs, + ) -> PeAudioVideoOutput: + if sum([input_ids is not None, pixel_values_videos is not None, input_values is not None]) < 2: + raise ValueError("At least two of input_ids, pixel_values_videos, or input_values must be provided") + + if pixel_values_videos is None: + outputs = self.audio_model( + input_ids=input_ids, + input_values=input_values, + attention_mask=attention_mask, + padding_mask=padding_mask, + return_dict=True, + ) + audio_plus_text_embeds = torch.cat( + [outputs.audio_outputs.pooler_output, outputs.text_outputs.hidden_states[-1][:, 0]], dim=-1 + ) + audio_plus_text_embeds = self.audio_plus_text_head(audio_plus_text_embeds) + return PeAudioVideoOutput(audio_plus_text_embeds=audio_plus_text_embeds, **outputs) + + if input_values is None: + outputs = self.video_model( + input_ids=input_ids, + pixel_values_videos=pixel_values_videos, + attention_mask=attention_mask, + padding_mask_videos=padding_mask_videos, + return_dict=True, + ) + video_plus_text_embeds = torch.cat( + [outputs.video_outputs.pooler_output, outputs.text_outputs.hidden_states[-1][:, 0]], dim=-1 + ) + video_plus_text_embeds = self.video_plus_text_head(video_plus_text_embeds) + return PeAudioVideoOutput(video_plus_text_embeds=video_plus_text_embeds, **outputs) + + audio_video_outputs = self.audio_video_encoder( + input_values=input_values, + pixel_values_videos=pixel_values_videos, + padding_mask=padding_mask, + padding_mask_videos=padding_mask_videos, + **kwargs, + ) + audio_embeds = audio_video_outputs.audio_model_output.pooler_output + video_embeds = audio_video_outputs.video_model_output.pooler_output + audio_video_embeds = audio_video_outputs.pooler_output + + audio_embeds = self.audio_model.audio_head(audio_embeds) + video_embeds = self.video_model.video_head(video_embeds) + audio_video_embeds = self.audio_video_head(audio_video_embeds) + logits_audio_video = audio_embeds @ video_embeds.T + logits_audio_video = logits_audio_video * self.audio_video_logit_scale + self.audio_video_logit_bias + audio_video_loss = self._contrastive_loss(logits_audio_video) if return_loss else None + + if input_ids is None: + return PeAudioVideoOutput( + logits_audio_video=logits_audio_video, + audio_embeds=audio_embeds, + video_embeds=video_embeds, + audio_video_embeds=audio_video_embeds, + loss=audio_video_loss, + audio_video_loss=audio_video_loss, + ) + + kwargs["output_hidden_states"] = True + text_outputs = self.text_model(input_ids=input_ids, attention_mask=attention_mask, **kwargs) + text_embeds = text_outputs.hidden_states[-1][:, 0] + audio_plus_text_embeds = torch.cat([audio_video_outputs.audio_model_output.pooler_output, text_embeds], dim=-1) + video_plus_text_embeds = torch.cat([audio_video_outputs.video_model_output.pooler_output, text_embeds], dim=-1) + + text_audio_embeds = self.audio_model.text_audio_head(text_embeds) + text_video_embeds = self.video_model.text_video_head(text_embeds) + text_audio_video_embeds = self.text_audio_video_head(text_embeds) + audio_plus_text_embeds = self.audio_plus_text_head(audio_plus_text_embeds) + video_plus_text_embeds = self.video_plus_text_head(video_plus_text_embeds) + + logits_audio_text = audio_embeds @ text_audio_embeds.T + logits_video_text = video_embeds @ text_video_embeds.T + logits_audio_video_text = audio_video_embeds @ text_audio_video_embeds.T + + logits_audio_plus_text_video = audio_plus_text_embeds @ video_embeds.T + logits_video_plus_text_audio = video_plus_text_embeds @ audio_embeds.T + + logits_audio_text = ( + logits_audio_text * self.audio_model.text_audio_logit_scale + self.audio_model.text_audio_logit_bias + ) + logits_video_text = ( + logits_video_text * self.video_model.text_video_logit_scale + self.video_model.text_video_logit_bias + ) + logits_audio_video_text = ( + logits_audio_video_text * self.text_audio_video_logit_scale + self.text_audio_video_logit_bias + ) + + logits_audio_plus_text_video = ( + logits_audio_plus_text_video * self.audio_plus_text_logit_scale + self.audio_plus_text_logit_bias + ) + logits_video_plus_text_audio = ( + logits_video_plus_text_audio * self.video_plus_text_logit_scale + self.video_plus_text_logit_bias + ) + + if return_loss: + audio_text_loss = self._contrastive_loss(logits_audio_text) + video_text_loss = self._contrastive_loss(logits_video_text) + audio_video_text_loss = self._contrastive_loss(logits_audio_video_text) + audio_plus_text_video_loss = self._contrastive_loss(logits_audio_plus_text_video) + video_plus_text_audio_loss = self._contrastive_loss(logits_video_plus_text_audio) + loss = ( + audio_video_text_loss + + audio_text_loss + + video_text_loss + + audio_video_loss + + audio_plus_text_video_loss + + video_plus_text_audio_loss + ) + + return PeAudioVideoOutput( + # embeddings + audio_embeds=audio_embeds, + video_embeds=video_embeds, + audio_video_embeds=audio_video_embeds, + text_audio_embeds=text_audio_embeds, + text_video_embeds=text_video_embeds, + text_audio_video_embeds=text_audio_video_embeds, + audio_plus_text_embeds=audio_plus_text_embeds, + video_plus_text_embeds=video_plus_text_embeds, + # model outputs + text_outputs=text_outputs, + audio_outputs=audio_video_outputs.audio_model_output, + video_outputs=audio_video_outputs.video_model_output, + audio_video_outputs=audio_video_outputs, + # logits + logits_audio_text=logits_audio_text, + logits_video_text=logits_video_text, + logits_audio_video=logits_audio_video, + logits_audio_video_text=logits_audio_video_text, + logits_audio_plus_text_video=logits_audio_plus_text_video, + logits_video_plus_text_audio=logits_video_plus_text_audio, + # losses + audio_text_loss=audio_text_loss if return_loss else None, + video_text_loss=video_text_loss if return_loss else None, + audio_video_loss=audio_video_loss if return_loss else None, + audio_video_text_loss=audio_video_text_loss if return_loss else None, + audio_plus_text_video_loss=audio_plus_text_video_loss if return_loss else None, + video_plus_text_audio_loss=video_plus_text_audio_loss if return_loss else None, + loss=loss if return_loss else None, + ) + + +__all__ = [ + "PeAudioVideoModel", + "PeAudioVideoEncoder", +] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pe_audio_video/processing_pe_audio_video.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pe_audio_video/processing_pe_audio_video.py new file mode 100644 index 0000000000000000000000000000000000000000..a03b213b10c540bdb74603ef86e7af10d2935ef6 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pe_audio_video/processing_pe_audio_video.py @@ -0,0 +1,24 @@ +# Copyright 2025 the HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from ...processing_utils import ProcessorMixin + + +class PeAudioVideoProcessor(ProcessorMixin): + attributes = ["feature_extractor", "video_processor", "tokenizer"] + feature_extractor_class = "PeAudioFeatureExtractor" + tokenizer_class = "AutoTokenizer" + video_processor_class = "PeVideoVideoProcessor" + + +__all__ = ["PeAudioVideoProcessor"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pe_video/__init__.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pe_video/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..b3ac2f050915f88e8b1593c704e8b6fed8a25653 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pe_video/__init__.py @@ -0,0 +1,29 @@ +# Copyright 2025 the HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from typing import TYPE_CHECKING + +from ...utils import _LazyModule +from ...utils.import_utils import define_import_structure + + +if TYPE_CHECKING: + from .configuration_pe_video import * + from .modeling_pe_video import * + from .processing_pe_video import * + from .video_processing_pe_video import * +else: + import sys + + _file = globals()["__file__"] + sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__) diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pe_video/configuration_pe_video.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pe_video/configuration_pe_video.py new file mode 100644 index 0000000000000000000000000000000000000000..cd3e2db34c4a8a4b59f837ead5217544a3e221d7 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pe_video/configuration_pe_video.py @@ -0,0 +1,209 @@ +# Copyright 2025 the HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +from ...configuration_utils import PreTrainedConfig, PretrainedConfig +from ...modeling_rope_utils import RopeParameters +from ...utils import logging +from ..auto import CONFIG_MAPPING, AutoConfig +from ..timm_wrapper import TimmWrapperConfig + + +logger = logging.get_logger(__name__) + + +class PeVideoEncoderConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`PeVideoEncoder`]. It is used to instantiate a + PeVideoEncoder model according to the specified arguments, defining the model architecture. Instantiating a configuration + with the defaults will yield a similar configuration to that of pe-av-large. + e.g. [facebook/pe-av-large](https://huggingface.co/facebook/pe-av-large) + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + + Args: + vision_config (`Union[PreTrainedConfig, dict]`, *optional*): + Configuration for the vision backbone used to extract frame embeddings. If a dictionary is provided, it is + used to instantiate a [`~transformers.TimmWrapperConfig`] with the PE default arguments. + hidden_size (`int`, *optional*, defaults to 1792): + Dimension of the hidden representations. + intermediate_size (`int`, *optional*, defaults to 4800): + Dimension of the feedforward layers in the Transformer blocks. + num_hidden_layers (`int`, *optional*, defaults to 6): + Number of Transformer encoder blocks. + num_attention_heads (`int`, *optional*, defaults to 14): + Number of attention heads used in each attention layer. + num_key_value_heads (`int`, *optional*): + Number of key and value heads for grouped-query attention. If unset, this defaults to `num_attention_heads`. + head_dim (`int`, *optional*, defaults to 128): + Dimension of each attention head for query, key, and value projections. + hidden_act (`str`, *optional*, defaults to `"silu"`): + The non-linear activation function (function or string) in the Transformer blocks. + max_position_embeddings (`int`, *optional*, defaults to 10000): + Maximum sequence length supported by the rotary position embeddings. + initializer_range (`float`, *optional*, defaults to 0.02): + Standard deviation of the truncated normal initializer for weight matrices. + rms_norm_eps (`float`, *optional*, defaults to 1e-05): + Epsilon used by the RMS normalization layers. + rope_parameters (`Union[RopeParameters, dict]`, *optional*, defaults to `{'rope_theta': 20000}`): + Parameters for the rotary position embeddings, such as the base `rope_theta`. + attention_bias (`bool`, *optional*, defaults to `False`): + Whether to use bias terms in the query, key, value, and output projections. + attention_dropout (`float`, *optional*, defaults to 0.0): + Dropout ratio applied to attention probabilities. + + ```python + >>> from transformers import PeAudioEncoder, PeAudioEncoderConfig + + >>> # Initializing a PeAudioEncoder style configuration + >>> configuration = PeAudioEncoderConfig() + + >>> # Initializing a model from the pe-av-large style configuration + >>> model = PeAudioEncoder(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "pe_video_encoder" + sub_configs = {"vision_config": TimmWrapperConfig} + base_config_key = "audio_video_config" + + _default_vision_config_kwargs = { + "architecture": "vit_pe_core_large_patch14_336", + "do_pooling": True, + "num_classes": 1024, + "global_pool": "map", + "initializer_range": 0.02, + } + + def __init__( + self, + vision_config: dict | PreTrainedConfig | None = None, + hidden_size: int | None = 1792, + intermediate_size: int | None = 4800, + num_hidden_layers: int | None = 6, + num_attention_heads: int | None = 14, + num_key_value_heads: int | None = None, + head_dim: int | None = 128, + hidden_act: str | None = "silu", + max_position_embeddings: int | None = 10000, + initializer_range: float | None = 0.02, + rms_norm_eps: float | None = 1e-5, + rope_parameters: RopeParameters | dict | None = {"rope_theta": 20000}, + attention_bias: bool | None = False, + attention_dropout: float | None = 0.0, + **kwargs, + ): + self.hidden_size = hidden_size + self.intermediate_size = intermediate_size + self.num_hidden_layers = num_hidden_layers + self.num_attention_heads = num_attention_heads + + # for backward compatibility + if num_key_value_heads is None: + num_key_value_heads = num_attention_heads + + self.num_key_value_heads = num_key_value_heads + self.head_dim = head_dim + self.hidden_act = hidden_act + self.max_position_embeddings = max_position_embeddings + self.initializer_range = initializer_range + self.rms_norm_eps = rms_norm_eps + self.rope_parameters = rope_parameters + self.attention_bias = attention_bias + self.attention_dropout = attention_dropout + + if isinstance(vision_config, dict): + vision_config["model_type"] = vision_config.get("model_type", "timm_wrapper") + vision_config = CONFIG_MAPPING[vision_config["model_type"]].from_dict( + {**self._default_vision_config_kwargs, **vision_config} + ) + elif vision_config is None: + vision_config = CONFIG_MAPPING["timm_wrapper"].from_dict(self._default_vision_config_kwargs) + + self.vision_config = vision_config + + super().__init__(**kwargs) + + +class PeVideoConfig(PretrainedConfig): + r""" + This is the configuration class to store the configuration of a [`PeVideoModel`]. It is used to instantiate a + PeVideoModel model according to the specified arguments, defining the model architecture. Instantiating a configuration + with the defaults will yield a similar configuration to that of pe-av-large. + e.g. [facebook/pe-av-large](https://huggingface.co/facebook/pe-av-large) + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + + Args: + text_config (`dict` or `PreTrainedConfig`, *optional*): + Configuration for the text model component. + video_config (`dict` or `PreTrainedConfig`, *optional*): + Configuration for the video encoder component. + + ```python + >>> from transformers import PeVideoModel, PeVideoConfig + + >>> # Initializing a PeVideoModel style configuration + >>> configuration = PeVideoConfig() + + >>> # Initializing a model from the pe-av-large style configuration + >>> model = PeVideoModel(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "pe_video" + sub_configs = {"text_config": AutoConfig, "video_config": PeVideoEncoderConfig} + base_config_key = "audio_video_config" + + _default_text_config_kwargs = { + "model_type": "modernbert", + "hidden_size": 1024, + "intermediate_size": 2624, + "num_hidden_layers": 22, + "num_attention_heads": 16, + } + + def __init__( + self, + text_config=None, + video_config=None, + **kwargs, + ): + if isinstance(text_config, dict): + text_config["model_type"] = text_config.get("model_type", "modernbert") + text_config = CONFIG_MAPPING[text_config["model_type"]]( + **{**self._default_text_config_kwargs, **text_config} + ) + elif text_config is None: + text_config = CONFIG_MAPPING["modernbert"](**self._default_text_config_kwargs) + + if isinstance(video_config, dict): + video_config = PeVideoEncoderConfig(**video_config) + elif video_config is None: + video_config = PeVideoEncoderConfig() + + self.text_config = text_config + self.video_config = video_config + + super().__init__(**kwargs) + + +__all__ = ["PeVideoEncoderConfig", "PeVideoConfig"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pe_video/modeling_pe_video.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pe_video/modeling_pe_video.py new file mode 100644 index 0000000000000000000000000000000000000000..fbc32ed0983dce3121b5c8e9025c122ec923e72c --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pe_video/modeling_pe_video.py @@ -0,0 +1,652 @@ +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# This file was automatically generated from src/transformers/models/pe_video/modular_pe_video.py. +# Do NOT edit this file manually as any edits will be overwritten by the generation of +# the file from the modular. If any change should be done, please apply the change to the +# modular_pe_video.py file directly. One of our CI enforces this. +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# Copyright 2025 the HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from collections.abc import Callable +from dataclasses import dataclass +from typing import Any, Optional + +import torch +import torch.nn as nn +import torch.nn.functional as F + +from ... import initialization as init +from ...activations import ACT2FN +from ...cache_utils import Cache +from ...integrations import use_kernel_forward_from_hub, use_kernelized_func +from ...masking_utils import create_bidirectional_mask +from ...modeling_layers import GradientCheckpointingLayer +from ...modeling_outputs import BaseModelOutputWithPooling, MaskedLMOutput +from ...modeling_rope_utils import ROPE_INIT_FUNCTIONS, dynamic_rope_update +from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel +from ...processing_utils import Unpack +from ...utils import ModelOutput, TransformersKwargs, auto_docstring, can_return_tuple +from ...utils.generic import maybe_autocast, merge_with_config_defaults +from ...utils.output_capturing import capture_outputs +from ..auto import AutoModel, AutoModelForImageClassification +from .configuration_pe_video import PeVideoConfig, PeVideoEncoderConfig + + +# TODO: not sure about the typing for text_model_output +@dataclass +# @auto_docstring +class PeVideoOutput(ModelOutput): + loss: torch.FloatTensor | None = None + logits_video_text: torch.FloatTensor | None = None + text_video_embeds: torch.FloatTensor | None = None + video_embeds: torch.FloatTensor | None = None + text_outputs: BaseModelOutputWithPooling = None + video_outputs: BaseModelOutputWithPooling = None + + def to_tuple(self) -> tuple[Any]: + return tuple( + self[k] if k not in ["text_outputs", "video_outputs"] else getattr(self, k).to_tuple() for k in self.keys() + ) + + +class PeVideoContrastiveHead(nn.Module): + def __init__( + self, + in_dim: int, + out_dim: int, + ) -> None: + super().__init__() + self.layer_norm = nn.LayerNorm(normalized_shape=in_dim, eps=1e-6) + self.proj = nn.Linear(in_dim, out_dim, bias=False) + + def forward(self, x: torch.Tensor) -> torch.FloatTensor: + return self.proj(self.layer_norm(x)) + + +class PeVideoMaskedGroupNorm(nn.GroupNorm): + def forward(self, x, padding_mask=None): + if padding_mask is None: + return super().forward(x) + + batch_size, hidden_size, seq_len = x.shape + group_size = hidden_size // self.num_groups + grouped_shape = (batch_size, -1, group_size, seq_len) + + x_grouped = x.view(grouped_shape) + padding_mask_grouped = padding_mask.reshape(grouped_shape).bool() + + mean = torch.masked.mean(x_grouped, mask=padding_mask_grouped, dim=(2, 3), keepdim=True) + var = torch.masked.var(x_grouped, mask=padding_mask_grouped, dim=(2, 3), keepdim=True, unbiased=False) + + x_norm = (x_grouped - mean) / torch.sqrt(var + self.eps) + x_norm = x_norm.view(x.shape) + + if self.affine: + x_norm = x_norm * self.weight.view(1, -1, 1) + self.bias.view(1, -1, 1) + + return x_norm * padding_mask + + +class PeVideoConvBlock1d(nn.Module): + def __init__(self, config): + super().__init__() + self.groupnorm = PeVideoMaskedGroupNorm(num_groups=1, num_channels=config.hidden_size) + self.activation = nn.SiLU() + self.project = nn.Conv1d( + in_channels=config.hidden_size, + out_channels=config.hidden_size, + kernel_size=3, + padding="same", + ) + + def forward(self, x, padding_mask=None): + x = self.groupnorm(x, padding_mask=padding_mask) + x = self.activation(x) + return self.project(x) + + +class PeVideoResnetBlock1d(nn.Module): + def __init__(self, config): + super().__init__() + self.block1 = PeVideoConvBlock1d(config) + self.block2 = PeVideoConvBlock1d(config) + + def forward(self, hidden_states, padding_mask=None): + """ + Args: + hidden_states: (batch_size, seq_len, hidden_size) + padding_mask: (batch_size, seq_len) + Returns: + hidden_states: (batch_size, seq_len, hidden_size) + """ + # transpose for convolutions + # (batch_size, seq_len, hidden_size) -> (batch_size, hidden_size, seq_len) + hidden_states = hidden_states.transpose(1, 2) + + if padding_mask is not None: + padding_mask = padding_mask.unsqueeze(1).expand_as(hidden_states) + + residual = hidden_states + hidden_states = self.block1(hidden_states, padding_mask=padding_mask) + hidden_states = self.block2(hidden_states, padding_mask=padding_mask) + hidden_states = residual + hidden_states + + return hidden_states.transpose(1, 2) + + +class PeVideoEncoderPatchEmbedder(nn.Module): + def __init__(self, config): + super().__init__() + self.resnet_block = PeVideoResnetBlock1d(config) + self.class_embedding = nn.Parameter(torch.randn(1, 1, config.hidden_size)) + + def forward(self, inputs_embeds, padding_mask=None): + # Embedding step: prepend class token and run the ResNet block. + hidden_states = torch.cat( + [self.class_embedding.expand(inputs_embeds.size(0), -1, -1), inputs_embeds], + dim=1, + ) + + if padding_mask is not None: + # TODO: any reason why we take padding_mask[0] and not just 1? + padding_mask = torch.cat([padding_mask[:, [0]], padding_mask], dim=1) + + hidden_states = self.resnet_block(hidden_states, padding_mask=padding_mask) + return hidden_states, padding_mask + + +class PeVideoEncoderEmbedder(nn.Module): + def __init__(self, config: PeVideoEncoderConfig): + super().__init__() + self.vision_model = AutoModelForImageClassification.from_config(config.vision_config) + self.proj = nn.Linear(config.vision_config.num_labels, config.hidden_size, bias=False) + self.data_proj = nn.Linear(config.hidden_size, config.hidden_size) + + def forward( + self, + pixel_values_videos: torch.Tensor, + padding_mask: torch.Tensor | None = None, + ) -> tuple[torch.Tensor, torch.Tensor | None]: + input_shape = pixel_values_videos.shape + + pixel_values_videos = pixel_values_videos.view(-1, *input_shape[2:]) + vision_encoder_outputs = self.vision_model(pixel_values_videos) + + logits = vision_encoder_outputs.logits.view(*input_shape[:2], -1) + logits = F.normalize(logits, dim=-1) + + vision_features = self.proj(logits) + inputs_embeds = self.data_proj(vision_features) + + return inputs_embeds, padding_mask + + +def repeat_kv(hidden_states: torch.Tensor, n_rep: int) -> torch.Tensor: + """ + This is the equivalent of torch.repeat_interleave(x, dim=1, repeats=n_rep). The hidden states go from (batch, + num_key_value_heads, seqlen, head_dim) to (batch, num_attention_heads, seqlen, head_dim) + """ + batch, num_key_value_heads, slen, head_dim = hidden_states.shape + if n_rep == 1: + return hidden_states + hidden_states = hidden_states[:, :, None, :, :].expand(batch, num_key_value_heads, n_rep, slen, head_dim) + return hidden_states.reshape(batch, num_key_value_heads * n_rep, slen, head_dim) + + +def eager_attention_forward( + module: nn.Module, + query: torch.Tensor, + key: torch.Tensor, + value: torch.Tensor, + attention_mask: torch.Tensor | None, + scaling: float, + dropout: float = 0.0, + **kwargs: Unpack[TransformersKwargs], +): + key_states = repeat_kv(key, module.num_key_value_groups) + value_states = repeat_kv(value, module.num_key_value_groups) + + attn_weights = torch.matmul(query, key_states.transpose(2, 3)) * scaling + if attention_mask is not None: + attn_weights = attn_weights + attention_mask + + attn_weights = nn.functional.softmax(attn_weights, dim=-1, dtype=torch.float32).to(query.dtype) + attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training) + attn_output = torch.matmul(attn_weights, value_states) + attn_output = attn_output.transpose(1, 2).contiguous() + + return attn_output, attn_weights + + +def stack_freqs(cos: torch.Tensor, sin: torch.Tensor): + dim = cos.size(-1) + cos = cos.narrow(-1, 0, dim // 2) + sin = sin.narrow(-1, 0, dim // 2) + freqs_cis = torch.stack((cos, -sin, sin, cos), dim=-1).view(*cos.size(), 2, 2) + return freqs_cis + + +def apply_rotary_pos_emb(q, k, cos, sin, unsqueeze_dim=1): + freqs_cis = stack_freqs(cos, sin) + freqs_cis = freqs_cis.unsqueeze(unsqueeze_dim) + q_ = q.reshape(*q.shape[:-1], -1, 1, 2) + k_ = k.reshape(*k.shape[:-1], -1, 1, 2) + return (q_ * freqs_cis).sum(5).flatten(3), (k_ * freqs_cis).sum(5).flatten(3) + + +@use_kernel_forward_from_hub("RMSNorm") +class PeVideoEncoderRMSNorm(nn.Module): + def __init__(self, hidden_size, eps: float = 1e-6) -> None: + """ + PeVideoEncoderRMSNorm is equivalent to T5LayerNorm + """ + super().__init__() + self.weight = nn.Parameter(torch.ones(hidden_size)) + self.variance_epsilon = eps + + def forward(self, hidden_states: torch.Tensor) -> torch.Tensor: + input_dtype = hidden_states.dtype + hidden_states = hidden_states.to(torch.float32) + variance = hidden_states.pow(2).mean(-1, keepdim=True) + hidden_states = hidden_states * torch.rsqrt(variance + self.variance_epsilon) + return self.weight * hidden_states.to(input_dtype) + + def extra_repr(self): + return f"{tuple(self.weight.shape)}, eps={self.variance_epsilon}" + + +@use_kernelized_func(apply_rotary_pos_emb) +class PeVideoEncoderAttention(nn.Module): + """Multi-headed attention from 'Attention Is All You Need' paper""" + + def __init__(self, config, layer_idx): + super().__init__() + self.layer_type = config.layer_types[layer_idx] if hasattr(config, "layer_types") else None + self.config = config + self.layer_idx = layer_idx + self.head_dim = getattr(config, "head_dim", config.hidden_size // config.num_attention_heads) + self.num_key_value_groups = config.num_attention_heads // config.num_key_value_heads + self.scaling = self.head_dim**-0.5 + self.attention_dropout = config.attention_dropout + self.is_causal = False + + self.q_proj = nn.Linear( + config.hidden_size, config.num_attention_heads * self.head_dim, bias=config.attention_bias + ) + self.k_proj = nn.Linear( + config.hidden_size, config.num_key_value_heads * self.head_dim, bias=config.attention_bias + ) + self.v_proj = nn.Linear( + config.hidden_size, config.num_key_value_heads * self.head_dim, bias=config.attention_bias + ) + self.o_proj = nn.Linear( + config.num_attention_heads * self.head_dim, config.hidden_size, bias=config.attention_bias + ) + self.q_norm = PeVideoEncoderRMSNorm( + self.head_dim, eps=config.rms_norm_eps + ) # unlike olmo, only on the head dim! + self.k_norm = PeVideoEncoderRMSNorm( + self.head_dim, eps=config.rms_norm_eps + ) # thus post q_norm does not need reshape + + def forward( + self, + hidden_states: torch.Tensor, + position_embeddings: tuple[torch.Tensor, torch.Tensor] | None = None, + attention_mask: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor, torch.Tensor]: + input_shape = hidden_states.shape[:-1] + hidden_shape = (*input_shape, -1, self.head_dim) + + query_states = self.q_norm(self.q_proj(hidden_states).view(hidden_shape)).transpose(1, 2) + key_states = self.k_norm(self.k_proj(hidden_states).view(hidden_shape)).transpose(1, 2) + value_states = self.v_proj(hidden_states).view(hidden_shape).transpose(1, 2) + + cos, sin = position_embeddings + query_states, key_states = apply_rotary_pos_emb(query_states, key_states, cos, sin) + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, eager_attention_forward + ) + + attn_output, attn_weights = attention_interface( + self, + query_states, + key_states, + value_states, + attention_mask, + dropout=0.0 if not self.training else self.attention_dropout, + scaling=self.scaling, + **kwargs, + ) + + attn_output = attn_output.reshape(*input_shape, -1).contiguous() + attn_output = self.o_proj(attn_output) + return attn_output, attn_weights + + +class PeVideoEncoderMLP(nn.Module): + def __init__(self, config): + super().__init__() + self.config = config + self.hidden_size = config.hidden_size + self.intermediate_size = config.intermediate_size + self.gate_proj = nn.Linear(self.hidden_size, self.intermediate_size, bias=False) + self.up_proj = nn.Linear(self.hidden_size, self.intermediate_size, bias=False) + self.down_proj = nn.Linear(self.intermediate_size, self.hidden_size, bias=False) + self.act_fn = ACT2FN[config.hidden_act] + + def forward(self, x): + down_proj = self.down_proj(self.act_fn(self.gate_proj(x)) * self.up_proj(x)) + return down_proj + + +class PeVideoEncoderLayer(GradientCheckpointingLayer): + def __init__(self, config, layer_idx): + super().__init__() + self.hidden_size = config.hidden_size + + self.self_attn = PeVideoEncoderAttention(config=config, layer_idx=layer_idx) + + self.mlp = PeVideoEncoderMLP(config) + self.input_layernorm = PeVideoEncoderRMSNorm(config.hidden_size, eps=config.rms_norm_eps) + self.post_attention_layernorm = PeVideoEncoderRMSNorm(config.hidden_size, eps=config.rms_norm_eps) + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.Tensor | None = None, + position_ids: torch.LongTensor | None = None, + past_key_values: Cache | None = None, + use_cache: bool | None = False, + cache_position: torch.LongTensor | None = None, + position_embeddings: tuple[torch.Tensor, torch.Tensor] | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> torch.Tensor: + residual = hidden_states + hidden_states = self.input_layernorm(hidden_states) + # Self Attention + hidden_states, _ = self.self_attn( + hidden_states=hidden_states, + attention_mask=attention_mask, + position_ids=position_ids, + past_key_values=past_key_values, + use_cache=use_cache, + cache_position=cache_position, + position_embeddings=position_embeddings, + **kwargs, + ) + hidden_states = residual + hidden_states + + # Fully Connected + residual = hidden_states + hidden_states = self.post_attention_layernorm(hidden_states) + hidden_states = self.mlp(hidden_states) + hidden_states = residual + hidden_states + return hidden_states + + +@auto_docstring +class PeVideoPreTrainedModel(PreTrainedModel): + config: PeVideoConfig + base_model_prefix = "video_model" + supports_gradient_checkpointing = True + _no_split_modules = ["PeVideoEncoderLayer"] + _skip_keys_device_placement = ["past_key_values"] + _supports_flash_attn = True + _supports_sdpa = True + _supports_flex_attn = True + + _can_compile_fullgraph = True + _supports_attention_backend = True + _can_record_outputs = { + "hidden_states": PeVideoEncoderLayer, + "attentions": PeVideoEncoderAttention, + } + main_input_name = "pixel_values_videos" + + def _init_weights(self, module): + super()._init_weights(module) + + if hasattr(self.config, "initializer_range"): + std = self.config.initializer_range + else: + # 0.02 is the standard default value across the library + std = getattr(self.config.get_text_config(), "initializer_range", 0.02) + + if isinstance(module, PeVideoEncoderPatchEmbedder): + embed_dim = module.class_embedding.shape[-1] + init.normal_(module.class_embedding, mean=0.0, std=embed_dim**-0.5 * std) + + +class PeVideoEncoderRotaryEmbedding(nn.Module): + inv_freq: torch.Tensor # fix linting for `register_buffer` + + def __init__(self, config: PeVideoEncoderConfig, device=None): + super().__init__() + self.max_seq_len_cached = config.max_position_embeddings + self.original_max_seq_len = config.max_position_embeddings + + self.config = config + + self.rope_type = self.config.rope_parameters["rope_type"] + rope_init_fn: Callable = self.compute_default_rope_parameters + if self.rope_type != "default": + rope_init_fn = ROPE_INIT_FUNCTIONS[self.rope_type] + inv_freq, self.attention_scaling = rope_init_fn(self.config, device) + + self.register_buffer("inv_freq", inv_freq, persistent=False) + self.register_buffer("original_inv_freq", inv_freq.clone(), persistent=False) + + @staticmethod + def compute_default_rope_parameters( + config: PeVideoEncoderConfig | None = None, + device: Optional["torch.device"] = None, + seq_len: int | None = None, + ) -> tuple["torch.Tensor", float]: + """ + Computes the inverse frequencies according to the original RoPE implementation + Args: + config ([`~transformers.PreTrainedConfig`]): + The model configuration. + device (`torch.device`): + The device to use for initialization of the inverse frequencies. + seq_len (`int`, *optional*): + The current sequence length. Unused for this type of RoPE. + Returns: + Tuple of (`torch.Tensor`, `float`), containing the inverse frequencies for the RoPE embeddings and the + post-processing scaling factor applied to the computed cos/sin (unused in this type of RoPE). + """ + base = config.rope_parameters["rope_theta"] + dim = getattr(config, "head_dim", None) or config.hidden_size // config.num_attention_heads + + attention_factor = 1.0 # Unused in this type of RoPE + + # Compute the inverse frequencies + inv_freq = 1.0 / ( + base ** (torch.arange(0, dim, 2, dtype=torch.int64).to(device=device, dtype=torch.float) / dim) + ) + return inv_freq, attention_factor + + @torch.no_grad() + @dynamic_rope_update # power user: used with advanced RoPE types (e.g. dynamic rope) + def forward(self, x, position_ids): + inv_freq_expanded = self.inv_freq[None, :, None].float().expand(position_ids.shape[0], -1, 1).to(x.device) + position_ids_expanded = position_ids[:, None, :].float() + + device_type = x.device.type if isinstance(x.device.type, str) and x.device.type != "mps" else "cpu" + with maybe_autocast(device_type=device_type, enabled=False): # Force float32 + freqs = (inv_freq_expanded.float() @ position_ids_expanded.float()).transpose(1, 2) + emb = torch.cat((freqs, freqs), dim=-1) + cos = emb.cos() * self.attention_scaling + sin = emb.sin() * self.attention_scaling + + return cos.to(dtype=x.dtype), sin.to(dtype=x.dtype) + + +@auto_docstring( + custom_intro=""" + The PeVideo Encoder model. + """ +) +class PeVideoEncoder(PeVideoPreTrainedModel): + config: PeVideoEncoderConfig + main_input_name = "pixel_values_videos" + base_model_prefix = "video_model.video_encoder" + + def __init__(self, config: PeVideoEncoderConfig): + super().__init__(config) + self.embedder = PeVideoEncoderEmbedder(config) + self.patch_embedder = PeVideoEncoderPatchEmbedder(config) + self.layers = nn.ModuleList( + [PeVideoEncoderLayer(config, layer_idx) for layer_idx in range(config.num_hidden_layers)] + ) + self.norm = PeVideoEncoderRMSNorm(config.hidden_size, eps=config.rms_norm_eps) + self.rotary_emb = PeVideoEncoderRotaryEmbedding(config=config) + self.output = nn.Linear(config.hidden_size, config.hidden_size, bias=False) + self.gradient_checkpointing = False + + self.post_init() + + @can_return_tuple + @merge_with_config_defaults + @capture_outputs + def forward( + self, + pixel_values_videos: torch.Tensor, + padding_mask_videos: torch.Tensor | None = None, + **kwargs, + ) -> tuple | BaseModelOutputWithPooling: + inputs_embeds, padding_mask = self.embedder(pixel_values_videos, padding_mask=padding_mask_videos) + inputs_embeds, attention_mask = self.patch_embedder(inputs_embeds, padding_mask=padding_mask) + + if attention_mask is not None: + attention_mask = create_bidirectional_mask( + config=self.config, + inputs_embeds=inputs_embeds, + attention_mask=attention_mask, + ) + + position_ids = torch.arange(inputs_embeds.shape[1], device=inputs_embeds.device).unsqueeze(0) + position_embeddings = self.rotary_emb(inputs_embeds, position_ids) + + hidden_states = inputs_embeds + for encoder_layer in self.layers[: self.config.num_hidden_layers]: + hidden_states = encoder_layer( + hidden_states, + attention_mask=attention_mask, + position_embeddings=position_embeddings, + **kwargs, + ) + + hidden_states = self.norm(hidden_states) + hidden_states = self.output(hidden_states) + + return BaseModelOutputWithPooling( + last_hidden_state=hidden_states[:, 1:], + pooler_output=hidden_states[:, 0], + ) + + +class PeVideoModel(PeVideoPreTrainedModel): + main_input_name = "input_ids" + + def __init__(self, config: PeVideoConfig): + super().__init__(config) + self.text_model = AutoModel.from_config(config.text_config) + self.video_encoder = PeVideoEncoder(config.video_config) + + self.text_video_head = PeVideoContrastiveHead(config.text_config.hidden_size, config.text_config.hidden_size) + self.video_head = PeVideoContrastiveHead(config.video_config.hidden_size, config.text_config.hidden_size) + + self.text_video_logit_scale = nn.Parameter(torch.zeros(1)) + self.text_video_logit_bias = nn.Parameter(torch.zeros(1)) + + self.post_init() + + @can_return_tuple + @auto_docstring + def get_text_features( + self, + input_ids: torch.Tensor, + attention_mask: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple | BaseModelOutputWithPooling: + text_outputs: BaseModelOutputWithPooling = self.text_model( + input_ids=input_ids, + attention_mask=attention_mask, + return_dict=True, + **kwargs, + ) + text_outputs.pooler_output = self.text_video_head(text_outputs.last_hidden_state) + return text_outputs + + @can_return_tuple + @auto_docstring + def get_video_features( + self, + pixel_values_videos: torch.Tensor, + padding_mask_videos: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple | BaseModelOutputWithPooling: + video_outputs: BaseModelOutputWithPooling = self.video_encoder( + pixel_values_videos=pixel_values_videos, + padding_mask_videos=padding_mask_videos, + return_dict=True, + **kwargs, + ) + video_outputs.pooler_output = self.video_head(video_outputs.pooler_output) + return video_outputs + + @can_return_tuple + def forward( + self, + input_ids: torch.Tensor, + pixel_values_videos: torch.Tensor, + attention_mask: torch.Tensor | None = None, + padding_mask_videos: torch.Tensor | None = None, + return_loss: bool | None = None, + **kwargs, + ) -> PeVideoOutput: + video_outputs: BaseModelOutputWithPooling = self.video_encoder( + pixel_values_videos=pixel_values_videos, padding_mask_videos=padding_mask_videos, **kwargs + ) + kwargs["output_hidden_states"] = True + text_outputs: MaskedLMOutput = self.text_model(input_ids=input_ids, attention_mask=attention_mask, **kwargs) + + video_embeds = video_outputs.pooler_output + video_embeds = self.video_head(video_embeds) + + text_video_embeds = text_outputs.hidden_states[-1][:, 0] + text_video_embeds = self.text_video_head(text_video_embeds) + + logits_video_text = video_embeds @ text_video_embeds.T + logits_video_text = logits_video_text * self.text_video_logit_scale + self.text_video_logit_bias + + loss = None + if return_loss: + labels = torch.eye(logits_video_text.shape[0], device=logits_video_text.device) + loss = -F.logsigmoid(labels * logits_video_text).sum() / logits_video_text.shape[0] + + return PeVideoOutput( + logits_video_text=logits_video_text, + text_video_embeds=text_video_embeds, + video_embeds=video_embeds, + text_outputs=text_outputs, + video_outputs=video_outputs, + loss=loss, + ) + + +__all__ = ["PeVideoEncoder", "PeVideoModel"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pe_video/modular_pe_video.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pe_video/modular_pe_video.py new file mode 100644 index 0000000000000000000000000000000000000000..2c7764e6fe251cd55c2ee777ef5401f59a6fba1c --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pe_video/modular_pe_video.py @@ -0,0 +1,237 @@ +# Copyright 2025 the HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from dataclasses import dataclass +from typing import Any + +import torch +import torch.nn as nn +import torch.nn.functional as F + +from ...masking_utils import create_bidirectional_mask +from ...modeling_outputs import BaseModelOutputWithPooling, MaskedLMOutput +from ...processing_utils import Unpack +from ...utils import ModelOutput, TransformersKwargs, auto_docstring, can_return_tuple +from ...utils.generic import merge_with_config_defaults +from ...utils.output_capturing import capture_outputs +from ..auto import AutoModel, AutoModelForImageClassification +from ..pe_audio_video.modeling_pe_audio_video import ( + PeAudioVideoContrastiveHead, + PeAudioVideoEncoder, + PeAudioVideoEncoderPatchEmbedder, + PeAudioVideoPreTrainedModel, +) +from .configuration_pe_video import PeVideoConfig, PeVideoEncoderConfig + + +# TODO: not sure about the typing for text_model_output +@dataclass +# @auto_docstring +class PeVideoOutput(ModelOutput): + loss: torch.FloatTensor | None = None + logits_video_text: torch.FloatTensor | None = None + text_video_embeds: torch.FloatTensor | None = None + video_embeds: torch.FloatTensor | None = None + text_outputs: BaseModelOutputWithPooling = None + video_outputs: BaseModelOutputWithPooling = None + + def to_tuple(self) -> tuple[Any]: + return tuple( + self[k] if k not in ["text_outputs", "video_outputs"] else getattr(self, k).to_tuple() for k in self.keys() + ) + + +class PeVideoContrastiveHead(PeAudioVideoContrastiveHead): ... + + +class PeVideoEncoderPatchEmbedder(PeAudioVideoEncoderPatchEmbedder): ... + + +class PeVideoEncoderEmbedder(nn.Module): + def __init__(self, config: PeVideoEncoderConfig): + super().__init__() + self.vision_model = AutoModelForImageClassification.from_config(config.vision_config) + self.proj = nn.Linear(config.vision_config.num_labels, config.hidden_size, bias=False) + self.data_proj = nn.Linear(config.hidden_size, config.hidden_size) + + def forward( + self, + pixel_values_videos: torch.Tensor, + padding_mask: torch.Tensor | None = None, + ) -> tuple[torch.Tensor, torch.Tensor | None]: + input_shape = pixel_values_videos.shape + + pixel_values_videos = pixel_values_videos.view(-1, *input_shape[2:]) + vision_encoder_outputs = self.vision_model(pixel_values_videos) + + logits = vision_encoder_outputs.logits.view(*input_shape[:2], -1) + logits = F.normalize(logits, dim=-1) + + vision_features = self.proj(logits) + inputs_embeds = self.data_proj(vision_features) + + return inputs_embeds, padding_mask + + +class PeVideoPreTrainedModel(PeAudioVideoPreTrainedModel): + base_model_prefix = "video_model" + main_input_name = "pixel_values_videos" + + +@auto_docstring( + custom_intro=""" + The PeVideo Encoder model. + """ +) +class PeVideoEncoder(PeAudioVideoEncoder): + base_model_prefix = "video_model.video_encoder" + main_input_name = "pixel_values_videos" + + def __init__(self, config: PeVideoEncoderConfig): + super().__init__(config) + self.embedder = PeVideoEncoderEmbedder(config) + + @can_return_tuple + @merge_with_config_defaults + @capture_outputs + def forward( + self, + pixel_values_videos: torch.Tensor, + padding_mask_videos: torch.Tensor | None = None, + **kwargs, + ) -> tuple | BaseModelOutputWithPooling: + inputs_embeds, padding_mask = self.embedder(pixel_values_videos, padding_mask=padding_mask_videos) + inputs_embeds, attention_mask = self.patch_embedder(inputs_embeds, padding_mask=padding_mask) + + if attention_mask is not None: + attention_mask = create_bidirectional_mask( + config=self.config, + inputs_embeds=inputs_embeds, + attention_mask=attention_mask, + ) + + position_ids = torch.arange(inputs_embeds.shape[1], device=inputs_embeds.device).unsqueeze(0) + position_embeddings = self.rotary_emb(inputs_embeds, position_ids) + + hidden_states = inputs_embeds + for encoder_layer in self.layers[: self.config.num_hidden_layers]: + hidden_states = encoder_layer( + hidden_states, + attention_mask=attention_mask, + position_embeddings=position_embeddings, + **kwargs, + ) + + hidden_states = self.norm(hidden_states) + hidden_states = self.output(hidden_states) + + return BaseModelOutputWithPooling( + last_hidden_state=hidden_states[:, 1:], + pooler_output=hidden_states[:, 0], + ) + + +class PeVideoModel(PeVideoPreTrainedModel): + main_input_name = "input_ids" + + def __init__(self, config: PeVideoConfig): + super().__init__(config) + self.text_model = AutoModel.from_config(config.text_config) + self.video_encoder = PeVideoEncoder(config.video_config) + + self.text_video_head = PeVideoContrastiveHead(config.text_config.hidden_size, config.text_config.hidden_size) + self.video_head = PeVideoContrastiveHead(config.video_config.hidden_size, config.text_config.hidden_size) + + self.text_video_logit_scale = nn.Parameter(torch.zeros(1)) + self.text_video_logit_bias = nn.Parameter(torch.zeros(1)) + + self.post_init() + + @can_return_tuple + @auto_docstring + def get_text_features( + self, + input_ids: torch.Tensor, + attention_mask: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple | BaseModelOutputWithPooling: + text_outputs: BaseModelOutputWithPooling = self.text_model( + input_ids=input_ids, + attention_mask=attention_mask, + return_dict=True, + **kwargs, + ) + text_outputs.pooler_output = self.text_video_head(text_outputs.last_hidden_state) + return text_outputs + + @can_return_tuple + @auto_docstring + def get_video_features( + self, + pixel_values_videos: torch.Tensor, + padding_mask_videos: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple | BaseModelOutputWithPooling: + video_outputs: BaseModelOutputWithPooling = self.video_encoder( + pixel_values_videos=pixel_values_videos, + padding_mask_videos=padding_mask_videos, + return_dict=True, + **kwargs, + ) + video_outputs.pooler_output = self.video_head(video_outputs.pooler_output) + return video_outputs + + @can_return_tuple + def forward( + self, + input_ids: torch.Tensor, + pixel_values_videos: torch.Tensor, + attention_mask: torch.Tensor | None = None, + padding_mask_videos: torch.Tensor | None = None, + return_loss: bool | None = None, + **kwargs, + ) -> PeVideoOutput: + video_outputs: BaseModelOutputWithPooling = self.video_encoder( + pixel_values_videos=pixel_values_videos, padding_mask_videos=padding_mask_videos, **kwargs + ) + kwargs["output_hidden_states"] = True + text_outputs: MaskedLMOutput = self.text_model(input_ids=input_ids, attention_mask=attention_mask, **kwargs) + + video_embeds = video_outputs.pooler_output + video_embeds = self.video_head(video_embeds) + + text_video_embeds = text_outputs.hidden_states[-1][:, 0] + text_video_embeds = self.text_video_head(text_video_embeds) + + logits_video_text = video_embeds @ text_video_embeds.T + logits_video_text = logits_video_text * self.text_video_logit_scale + self.text_video_logit_bias + + loss = None + if return_loss: + labels = torch.eye(logits_video_text.shape[0], device=logits_video_text.device) + loss = -F.logsigmoid(labels * logits_video_text).sum() / logits_video_text.shape[0] + + return PeVideoOutput( + logits_video_text=logits_video_text, + text_video_embeds=text_video_embeds, + video_embeds=video_embeds, + text_outputs=text_outputs, + video_outputs=video_outputs, + loss=loss, + ) + + +__all__ = [ + "PeVideoEncoder", + "PeVideoModel", +] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pe_video/processing_pe_video.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pe_video/processing_pe_video.py new file mode 100644 index 0000000000000000000000000000000000000000..515311ca99413991eeef735a7784c768d297d65c --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pe_video/processing_pe_video.py @@ -0,0 +1,10 @@ +from ...processing_utils import ProcessorMixin + + +class PeVideoProcessor(ProcessorMixin): + attributes = ["video_processor", "tokenizer"] + video_processor_class = "PeVideoVideoProcessor" + tokenizer_class = "AutoTokenizer" + + +__all__ = ["PeVideoProcessor"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pe_video/video_processing_pe_video.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pe_video/video_processing_pe_video.py new file mode 100644 index 0000000000000000000000000000000000000000..82a6d0e1121e0b1c5051fed6ffb940ff1a2e18ad --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pe_video/video_processing_pe_video.py @@ -0,0 +1,64 @@ +# Copyright 2025 the HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import torch + +from ...image_processing_utils import BatchFeature +from ...image_utils import PILImageResampling +from ...processing_utils import Unpack, VideosKwargs +from ...video_processing_utils import BaseVideoProcessor, VideoMetadata +from ...video_utils import VideoInput + + +class PeVideoVideoProcessor(BaseVideoProcessor): + resample = PILImageResampling.BILINEAR + + def sample_frames( + self, + metadata: VideoMetadata, + num_frames: int | None = None, + fps: int | float | None = None, + **kwargs, + ): + if num_frames: + total_frames = metadata.total_num_frames + num_frames = num_frames if num_frames is not None else self.num_frames + assert num_frames is not None, "`num_frames` must be specified if `fixed_len_video == True`" + frame_idxs = [int(i * (total_frames - 1) / (num_frames - 1)) for i in range(num_frames)] + return torch.tensor(frame_idxs) + else: + return super().sample_frames(metadata, num_frames, fps, **kwargs) + + def _preprocess( + self, + videos: VideoInput, + **kwargs: Unpack[VideosKwargs], + ) -> BatchFeature: + # Always set `return_tensors` to `None` since it won't pad variable length videos + # We'll handle this after we call the parent' method + return_tensors = kwargs.pop("return_tensors", None) + result = super()._preprocess(videos, **kwargs) + pixels = result.pixel_values_videos + data = {"pixel_values_videos": pixels} + if return_tensors: + lengths = torch.tensor([video.size(0) for video in pixels]) + pixels = torch.nn.utils.rnn.pad_sequence(pixels, batch_first=True, padding_value=0.0) + data["pixel_values_videos"] = pixels + if lengths.unique().size(0) > 1: + mask = torch.arange(lengths.max())[None] < lengths[:, None] + data["padding_mask_videos"] = mask + return BatchFeature(data=data, tensor_type=return_tensors) + + +__all__ = ["PeVideoVideoProcessor"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pegasus/__init__.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pegasus/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..288776550986876700ee1702a34c11b388738d1f --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pegasus/__init__.py @@ -0,0 +1,28 @@ +# Copyright 2024 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from typing import TYPE_CHECKING + +from ...utils import _LazyModule +from ...utils.import_utils import define_import_structure + + +if TYPE_CHECKING: + from .configuration_pegasus import * + from .modeling_pegasus import * + from .tokenization_pegasus import * +else: + import sys + + _file = globals()["__file__"] + sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__) diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pegasus/configuration_pegasus.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pegasus/configuration_pegasus.py new file mode 100644 index 0000000000000000000000000000000000000000..b26412e89a88a0f7b5093e9f8b1655c7c052f57e --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pegasus/configuration_pegasus.py @@ -0,0 +1,159 @@ +# Copyright 2021, Google and The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""PEGASUS model configuration""" + +from ...configuration_utils import PreTrainedConfig +from ...utils import logging + + +logger = logging.get_logger(__name__) + + +class PegasusConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`PegasusModel`]. It is used to instantiate an + PEGASUS model according to the specified arguments, defining the model architecture. Instantiating a configuration + with the defaults will yield a similar configuration to that of the PEGASUS + [google/pegasus-large](https://huggingface.co/google/pegasus-large) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + + Args: + vocab_size (`int`, *optional*, defaults to 50265): + Vocabulary size of the PEGASUS model. Defines the number of different tokens that can be represented by the + `inputs_ids` passed when calling [`PegasusModel`]. + d_model (`int`, *optional*, defaults to 1024): + Dimensionality of the layers and the pooler layer. + encoder_layers (`int`, *optional*, defaults to 12): + Number of encoder layers. + decoder_layers (`int`, *optional*, defaults to 12): + Number of decoder layers. + encoder_attention_heads (`int`, *optional*, defaults to 16): + Number of attention heads for each attention layer in the Transformer encoder. + decoder_attention_heads (`int`, *optional*, defaults to 16): + Number of attention heads for each attention layer in the Transformer decoder. + decoder_ffn_dim (`int`, *optional*, defaults to 4096): + Dimensionality of the "intermediate" (often named feed-forward) layer in decoder. + encoder_ffn_dim (`int`, *optional*, defaults to 4096): + Dimensionality of the "intermediate" (often named feed-forward) layer in decoder. + activation_function (`str` or `function`, *optional*, defaults to `"gelu"`): + The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`, + `"relu"`, `"silu"` and `"gelu_new"` are supported. + dropout (`float`, *optional*, defaults to 0.1): + The dropout probability for all fully connected layers in the embeddings, encoder, and pooler. + attention_dropout (`float`, *optional*, defaults to 0.0): + The dropout ratio for the attention probabilities. + activation_dropout (`float`, *optional*, defaults to 0.0): + The dropout ratio for activations inside the fully connected layer. + max_position_embeddings (`int`, *optional*, defaults to 1024): + The maximum sequence length that this model might ever be used with. Typically set this to something large + just in case (e.g., 512 or 1024 or 2048). + init_std (`float`, *optional*, defaults to 0.02): + The standard deviation of the truncated_normal_initializer for initializing all weight matrices. + encoder_layerdrop (`float`, *optional*, defaults to 0.0): + The LayerDrop probability for the encoder. See the [LayerDrop paper](see https://huggingface.co/papers/1909.11556) + for more details. + decoder_layerdrop (`float`, *optional*, defaults to 0.0): + The LayerDrop probability for the decoder. See the [LayerDrop paper](see https://huggingface.co/papers/1909.11556) + for more details. + scale_embedding (`bool`, *optional*, defaults to `False`): + Scale embeddings by diving by sqrt(d_model). + use_cache (`bool`, *optional*, defaults to `True`): + Whether or not the model should return the last key/values attentions (not used by all models) + forced_eos_token_id (`int`, *optional*, defaults to 1): + The id of the token to force as the last generated token when `max_length` is reached. Usually set to + `eos_token_id`. + + Example: + + ```python + >>> from transformers import PegasusConfig, PegasusModel + + >>> # Initializing a PEGASUS google/pegasus-large style configuration + >>> configuration = PegasusConfig() + + >>> # Initializing a model (with random weights) from the google/pegasus-large style configuration + >>> model = PegasusModel(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "pegasus" + keys_to_ignore_at_inference = ["past_key_values"] + attribute_map = {"num_attention_heads": "encoder_attention_heads", "hidden_size": "d_model"} + + def __init__( + self, + vocab_size=50265, + max_position_embeddings=1024, + encoder_layers=12, + encoder_ffn_dim=4096, + encoder_attention_heads=16, + decoder_layers=12, + decoder_ffn_dim=4096, + decoder_attention_heads=16, + encoder_layerdrop=0.0, + decoder_layerdrop=0.0, + use_cache=True, + is_encoder_decoder=True, + activation_function="gelu", + d_model=1024, + dropout=0.1, + attention_dropout=0.0, + activation_dropout=0.0, + init_std=0.02, + decoder_start_token_id=0, + scale_embedding=False, + pad_token_id=0, + eos_token_id=1, + forced_eos_token_id=1, + is_decoder=False, + tie_word_embeddings=True, + **kwargs, + ): + self.is_decoder = is_decoder + self.tie_word_embeddings = tie_word_embeddings + self.vocab_size = vocab_size + self.max_position_embeddings = max_position_embeddings + self.d_model = d_model + self.encoder_ffn_dim = encoder_ffn_dim + self.encoder_layers = encoder_layers + self.encoder_attention_heads = encoder_attention_heads + self.decoder_ffn_dim = decoder_ffn_dim + self.decoder_layers = decoder_layers + self.decoder_attention_heads = decoder_attention_heads + self.dropout = dropout + self.attention_dropout = attention_dropout + self.activation_dropout = activation_dropout + self.activation_function = activation_function + self.init_std = init_std + self.encoder_layerdrop = encoder_layerdrop + self.decoder_layerdrop = decoder_layerdrop + self.use_cache = use_cache + self.num_hidden_layers = encoder_layers + self.scale_embedding = scale_embedding # scale factor will be sqrt(d_model) if True + self.pad_token_id = pad_token_id + self.eos_token_id = eos_token_id + self.decoder_start_token_id = decoder_start_token_id + self.forced_eos_token_id = forced_eos_token_id + super().__init__( + is_encoder_decoder=is_encoder_decoder, + **kwargs, + ) + + +__all__ = ["PegasusConfig"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pegasus/modeling_pegasus.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pegasus/modeling_pegasus.py new file mode 100644 index 0000000000000000000000000000000000000000..251ed33490436e66b8e2049ece645b346cafc15a --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pegasus/modeling_pegasus.py @@ -0,0 +1,1361 @@ +# Copyright 2021, Google and The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""PyTorch PEGASUS model.""" + +import copy +import math +from collections.abc import Callable + +import numpy as np +import torch +from torch import nn +from torch.nn import CrossEntropyLoss + +from ... import initialization as init +from ...activations import ACT2FN +from ...cache_utils import Cache, DynamicCache, EncoderDecoderCache +from ...generation import GenerationMixin +from ...masking_utils import create_bidirectional_mask, create_causal_mask +from ...modeling_flash_attention_utils import FlashAttentionKwargs +from ...modeling_layers import GradientCheckpointingLayer +from ...modeling_outputs import ( + BaseModelOutput, + BaseModelOutputWithPastAndCrossAttentions, + CausalLMOutputWithCrossAttentions, + Seq2SeqLMOutput, + Seq2SeqModelOutput, +) +from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel +from ...processing_utils import Unpack +from ...utils import ( + TransformersKwargs, + auto_docstring, + is_torchdynamo_compiling, + logging, +) +from .configuration_pegasus import PegasusConfig + + +logger = logging.get_logger(__name__) + + +# Copied from transformers.models.bart.modeling_bart.shift_tokens_right +def shift_tokens_right(input_ids: torch.Tensor, pad_token_id: int, decoder_start_token_id: int): + """ + Shift input ids one token to the right. + """ + shifted_input_ids = input_ids.new_zeros(input_ids.shape) + shifted_input_ids[:, 1:] = input_ids[:, :-1].clone() + shifted_input_ids[:, 0] = decoder_start_token_id + + if pad_token_id is None: + raise ValueError("self.model.config.pad_token_id has to be defined.") + # replace possible -100 values in labels by `pad_token_id` + shifted_input_ids.masked_fill_(shifted_input_ids == -100, pad_token_id) + + return shifted_input_ids + + +# Copied from transformers.models.marian.modeling_marian.MarianSinusoidalPositionalEmbedding with Marian->Pegasus +class PegasusSinusoidalPositionalEmbedding(nn.Embedding): + """This module produces sinusoidal positional embeddings of any length.""" + + def __init__(self, num_positions: int, embedding_dim: int, padding_idx: int | None = None) -> None: + super().__init__(num_positions, embedding_dim, _freeze=True) + + def create_weight(self): + """ + Identical to the XLM create_sinusoidal_embeddings except features are not interleaved. The cos features are in + the 2nd half of the vector. [dim // 2:] + """ + n_pos, dim = self.weight.shape + position_enc = np.array( + [[pos / np.power(10000, 2 * (j // 2) / dim) for j in range(dim)] for pos in range(n_pos)] + ) + out = torch.empty(n_pos, dim, dtype=self.weight.dtype, requires_grad=False) + sentinel = dim // 2 if dim % 2 == 0 else (dim // 2) + 1 + out[:, 0:sentinel] = torch.FloatTensor(np.sin(position_enc[:, 0::2])) + out[:, sentinel:] = torch.FloatTensor(np.cos(position_enc[:, 1::2])) + return out + + @torch.no_grad() + def forward( + self, input_ids_shape: torch.Size, past_key_values_length: int = 0, position_ids: torch.Tensor | None = None + ) -> torch.Tensor: + """`input_ids_shape` is expected to be [bsz x seqlen].""" + if position_ids is None: + bsz, seq_len = input_ids_shape[:2] + position_ids = torch.arange( + past_key_values_length, past_key_values_length + seq_len, dtype=torch.long, device=self.weight.device + ) + return super().forward(position_ids) + + +# Copied from transformers.models.bert.modeling_bert.eager_attention_forward +def eager_attention_forward( + module: nn.Module, + query: torch.Tensor, + key: torch.Tensor, + value: torch.Tensor, + attention_mask: torch.Tensor | None, + scaling: float | None = None, + dropout: float = 0.0, + **kwargs: Unpack[TransformersKwargs], +): + if scaling is None: + scaling = query.size(-1) ** -0.5 + + # Take the dot product between "query" and "key" to get the raw attention scores. + attn_weights = torch.matmul(query, key.transpose(2, 3)) * scaling + + if attention_mask is not None: + attn_weights = attn_weights + attention_mask + + attn_weights = nn.functional.softmax(attn_weights, dim=-1) + attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training) + + attn_output = torch.matmul(attn_weights, value) + attn_output = attn_output.transpose(1, 2).contiguous() + + return attn_output, attn_weights + + +# Copied from transformers.models.bart.modeling_bart.BartAttention with Bart->Pegasus +class PegasusAttention(nn.Module): + """Multi-headed attention from 'Attention Is All You Need' paper""" + + def __init__( + self, + embed_dim: int, + num_heads: int, + dropout: float = 0.0, + is_decoder: bool = False, + bias: bool = True, + is_causal: bool = False, + config: PegasusConfig | None = None, + layer_idx: int | None = None, + ): + super().__init__() + self.embed_dim = embed_dim + self.num_heads = num_heads + self.dropout = dropout + self.head_dim = embed_dim // num_heads + self.config = config + + if (self.head_dim * num_heads) != self.embed_dim: + raise ValueError( + f"embed_dim must be divisible by num_heads (got `embed_dim`: {self.embed_dim}" + f" and `num_heads`: {num_heads})." + ) + self.scaling = self.head_dim**-0.5 + self.is_decoder = is_decoder + self.is_causal = is_causal + self.layer_idx = layer_idx + if layer_idx is None and self.is_decoder: + logger.warning_once( + f"Instantiating a decoder {self.__class__.__name__} without passing `layer_idx` is not recommended and " + "will lead to errors during the forward call, if caching is used. Please make sure to provide a `layer_idx` " + "when creating this class." + ) + + self.k_proj = nn.Linear(embed_dim, embed_dim, bias=bias) + self.v_proj = nn.Linear(embed_dim, embed_dim, bias=bias) + self.q_proj = nn.Linear(embed_dim, embed_dim, bias=bias) + self.out_proj = nn.Linear(embed_dim, embed_dim, bias=bias) + + def forward( + self, + hidden_states: torch.Tensor, + key_value_states: torch.Tensor | None = None, + past_key_values: Cache | None = None, + attention_mask: torch.Tensor | None = None, + output_attentions: bool = False, + cache_position: torch.Tensor | None = None, + # TODO: we need a refactor so that the different attention modules can get their specific kwargs + # ATM, we have mixed things encoder, decoder, and encoder-decoder attn + **kwargs: Unpack[FlashAttentionKwargs], + ) -> tuple[torch.Tensor, torch.Tensor | None, tuple[torch.Tensor] | None]: + """Input shape: Batch x Time x Channel""" + + # if key_value_states are provided this layer is used as a cross-attention layer + # for the decoder + is_cross_attention = key_value_states is not None + + # determine input shapes + bsz, tgt_len = hidden_states.shape[:-1] + src_len = key_value_states.shape[1] if is_cross_attention else tgt_len + + q_input_shape = (bsz, tgt_len, -1, self.head_dim) + kv_input_shape = (bsz, src_len, -1, self.head_dim) + + # get query proj + query_states = self.q_proj(hidden_states).view(*q_input_shape).transpose(1, 2) + + is_updated = False + if past_key_values is not None: + if isinstance(past_key_values, EncoderDecoderCache): + is_updated = past_key_values.is_updated.get(self.layer_idx) + if is_cross_attention: + # after the first generated id, we can subsequently re-use all key/value_states from cache + curr_past_key_values = past_key_values.cross_attention_cache + else: + curr_past_key_values = past_key_values.self_attention_cache + else: + curr_past_key_values = past_key_values + + current_states = key_value_states if is_cross_attention else hidden_states + if is_cross_attention and past_key_values is not None and is_updated: + # reuse k,v, cross_attentions + key_states = curr_past_key_values.layers[self.layer_idx].keys + value_states = curr_past_key_values.layers[self.layer_idx].values + else: + key_states = self.k_proj(current_states) + value_states = self.v_proj(current_states) + key_states = key_states.view(*kv_input_shape).transpose(1, 2) + value_states = value_states.view(*kv_input_shape).transpose(1, 2) + + if past_key_values is not None: + # save all key/value_states to cache to be re-used for fast auto-regressive generation + cache_position = cache_position if not is_cross_attention else None + key_states, value_states = curr_past_key_values.update( + key_states, value_states, self.layer_idx, {"cache_position": cache_position} + ) + # set flag that curr layer for cross-attn is already updated so we can re-use in subsequent calls + if is_cross_attention and isinstance(past_key_values, EncoderDecoderCache): + past_key_values.is_updated[self.layer_idx] = True + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, eager_attention_forward + ) + + attn_output, attn_weights = attention_interface( + self, + query_states, + key_states, + value_states, + attention_mask, + dropout=0.0 if not self.training else self.dropout, + scaling=self.scaling, + output_attentions=output_attentions, + **kwargs, + ) + + attn_output = attn_output.reshape(bsz, tgt_len, -1).contiguous() + attn_output = self.out_proj(attn_output) + + return attn_output, attn_weights + + +# Copied from transformers.models.mbart.modeling_mbart.MBartEncoderLayer with MBart->Pegasus, MBART->PEGASUS +class PegasusEncoderLayer(GradientCheckpointingLayer): + def __init__(self, config: PegasusConfig): + super().__init__() + self.embed_dim = config.d_model + + self.self_attn = PegasusAttention( + embed_dim=self.embed_dim, + num_heads=config.encoder_attention_heads, + dropout=config.attention_dropout, + config=config, + ) + self.self_attn_layer_norm = nn.LayerNorm(self.embed_dim) + self.dropout = config.dropout + self.activation_fn = ACT2FN[config.activation_function] + self.activation_dropout = config.activation_dropout + self.fc1 = nn.Linear(self.embed_dim, config.encoder_ffn_dim) + self.fc2 = nn.Linear(config.encoder_ffn_dim, self.embed_dim) + self.final_layer_norm = nn.LayerNorm(self.embed_dim) + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.Tensor, + output_attentions: bool = False, + ) -> torch.Tensor: + """ + Args: + hidden_states (`torch.FloatTensor`): input to the layer of shape `(batch, seq_len, embed_dim)` + attention_mask (`torch.FloatTensor`): attention mask of size + `(batch, 1, tgt_len, src_len)` where padding elements are indicated by very large negative values. + output_attentions (`bool`, *optional*): + Whether or not to return the attentions tensors of all attention layers. See `attentions` under + returned tensors for more detail. + """ + residual = hidden_states + hidden_states = self.self_attn_layer_norm(hidden_states) + hidden_states, attn_weights = self.self_attn( + hidden_states=hidden_states, + attention_mask=attention_mask, + output_attentions=output_attentions, + ) + hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training) + hidden_states = residual + hidden_states + + residual = hidden_states + hidden_states = self.final_layer_norm(hidden_states) + hidden_states = self.activation_fn(self.fc1(hidden_states)) + hidden_states = nn.functional.dropout(hidden_states, p=self.activation_dropout, training=self.training) + hidden_states = self.fc2(hidden_states) + hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training) + hidden_states = residual + hidden_states + + if hidden_states.dtype == torch.float16: + clamp_value = torch.finfo(hidden_states.dtype).max - 1000 + hidden_states = torch.clamp(hidden_states, min=-clamp_value, max=clamp_value) + + return hidden_states, attn_weights + + +# Copied from transformers.models.mbart.modeling_mbart.MBartDecoderLayer with MBart->Pegasus, MBART->PEGASUS +class PegasusDecoderLayer(GradientCheckpointingLayer): + def __init__(self, config: PegasusConfig, layer_idx: int | None = None): + super().__init__() + self.embed_dim = config.d_model + + self.self_attn = PegasusAttention( + embed_dim=self.embed_dim, + num_heads=config.decoder_attention_heads, + dropout=config.attention_dropout, + is_decoder=True, + is_causal=True, + config=config, + layer_idx=layer_idx, + ) + self.dropout = config.dropout + self.activation_fn = ACT2FN[config.activation_function] + self.activation_dropout = config.activation_dropout + + self.self_attn_layer_norm = nn.LayerNorm(self.embed_dim) + self.encoder_attn = PegasusAttention( + self.embed_dim, + config.decoder_attention_heads, + dropout=config.attention_dropout, + is_decoder=True, + config=config, + layer_idx=layer_idx, + ) + self.encoder_attn_layer_norm = nn.LayerNorm(self.embed_dim) + self.fc1 = nn.Linear(self.embed_dim, config.decoder_ffn_dim) + self.fc2 = nn.Linear(config.decoder_ffn_dim, self.embed_dim) + self.final_layer_norm = nn.LayerNorm(self.embed_dim) + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.Tensor | None = None, + encoder_hidden_states: torch.Tensor | None = None, + encoder_attention_mask: torch.Tensor | None = None, + past_key_values: Cache | None = None, + output_attentions: bool | None = False, + use_cache: bool | None = True, + cache_position: torch.Tensor | None = None, + ) -> torch.Tensor: + """ + Args: + hidden_states (`torch.FloatTensor`): input to the layer of shape `(batch, seq_len, embed_dim)` + attention_mask (`torch.FloatTensor`): attention mask of size + `(batch, 1, tgt_len, src_len)` where padding elements are indicated by very large negative values. + encoder_hidden_states (`torch.FloatTensor`): + cross attention input to the layer of shape `(batch, seq_len, embed_dim)` + encoder_attention_mask (`torch.FloatTensor`): encoder attention mask of size + `(batch, 1, tgt_len, src_len)` where padding elements are indicated by very large negative values. + past_key_values (`Cache`): cached past key and value projection states + output_attentions (`bool`, *optional*): + Whether or not to return the attentions tensors of all attention layers. See `attentions` under + returned tensors for more detail. + cache_position (`torch.LongTensor` of shape `(sequence_length)`, *optional*): + Indices depicting the position of the input sequence tokens in the sequence. It is used to update the + cache in the correct position and to infer the complete sequence length. + """ + residual = hidden_states + hidden_states = self.self_attn_layer_norm(hidden_states) + + # Self Attention + hidden_states, self_attn_weights = self.self_attn( + hidden_states=hidden_states, + past_key_values=past_key_values, + attention_mask=attention_mask, + output_attentions=output_attentions, + cache_position=cache_position, + ) + hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training) + hidden_states = residual + hidden_states + + # Cross-Attention Block + cross_attn_weights = None + if encoder_hidden_states is not None: + residual = hidden_states + hidden_states = self.encoder_attn_layer_norm(hidden_states) + + hidden_states, cross_attn_weights = self.encoder_attn( + hidden_states=hidden_states, + key_value_states=encoder_hidden_states, + attention_mask=encoder_attention_mask, + past_key_values=past_key_values, + output_attentions=output_attentions, + ) + hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training) + hidden_states = residual + hidden_states + + # Fully Connected + residual = hidden_states + hidden_states = self.final_layer_norm(hidden_states) + hidden_states = self.activation_fn(self.fc1(hidden_states)) + hidden_states = nn.functional.dropout(hidden_states, p=self.activation_dropout, training=self.training) + hidden_states = self.fc2(hidden_states) + hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training) + hidden_states = residual + hidden_states + + outputs = (hidden_states,) + + if output_attentions: + outputs += (self_attn_weights, cross_attn_weights) + + return outputs + + +@auto_docstring +class PegasusPreTrainedModel(PreTrainedModel): + config: PegasusConfig + base_model_prefix = "model" + supports_gradient_checkpointing = True + _supports_flash_attn = True + _supports_sdpa = True + _supports_flex_attn = True + _can_compile_fullgraph = True + + @torch.no_grad() + def _init_weights(self, module): + super()._init_weights(module) + if isinstance(module, PegasusSinusoidalPositionalEmbedding): + init.copy_(module.weight, module.create_weight()) + elif isinstance(module, PegasusForConditionalGeneration): + init.zeros_(module.final_logits_bias) + + +class PegasusEncoder(PegasusPreTrainedModel): + """ + Transformer encoder consisting of *config.encoder_layers* self attention layers. Each layer is a + [`PegasusEncoderLayer`]. + + Args: + config: PegasusConfig + embed_tokens (nn.Embedding): output embedding + """ + + def __init__(self, config: PegasusConfig): + super().__init__(config) + + self.dropout = config.dropout + self.layerdrop = config.encoder_layerdrop + + embed_dim = config.d_model + self.padding_idx = config.pad_token_id + self.max_source_positions = config.max_position_embeddings + self.embed_scale = math.sqrt(embed_dim) if config.scale_embedding else 1.0 + + self.embed_tokens = nn.Embedding(config.vocab_size, embed_dim, self.padding_idx) + + self.embed_positions = PegasusSinusoidalPositionalEmbedding( + config.max_position_embeddings, + embed_dim, + self.padding_idx, + ) + self.layers = nn.ModuleList([PegasusEncoderLayer(config) for _ in range(config.encoder_layers)]) + self.layer_norm = nn.LayerNorm(config.d_model) + + self.gradient_checkpointing = False + # Initialize weights and apply final processing + self.post_init() + + def resize_position_embeddings(self, new_num_position_embeddings: int): + """ + Resizes position embeddings matrix of the model if `new_num_position_embeddings != + config.max_position_embeddings`. + + Arguments: + new_num_position_embeddings (`int`): + The number of new position embeddings. If position embeddings are learned, increasing the size will add + newly initialized vectors at the end, whereas reducing the size will remove vectors from the end. If + position embeddings are not learned (*e.g.* sinusoidal position embeddings), increasing the size will + add correct vectors at the end following the position encoding algorithm, whereas reducing the size + will remove vectors from the end. + """ + logger.info(f"Setting `config.max_position_embeddings={new_num_position_embeddings}`...") + self.config.max_position_embeddings = new_num_position_embeddings + + self.embed_positions = PegasusSinusoidalPositionalEmbedding( + self.config.max_position_embeddings, + self.config.d_model, + self.padding_idx, + ) + init.copy_(self.embed_positions.weight, self.embed_positions.create_weight()) + self.embed_positions.to(self.device) + + def get_position_embeddings(self) -> nn.Embedding: + """ + Returns the position embeddings matrix + """ + return self.embed_positions + + def forward( + self, + input_ids=None, + attention_mask=None, + inputs_embeds=None, + output_attentions=None, + output_hidden_states=None, + return_dict=None, + **kwargs, + ): + r""" + Args: + input_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`): + Indices of input sequence tokens in the vocabulary. Padding will be ignored by default should you + provide it. + + Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and + [`PreTrainedTokenizer.__call__`] for details. + + [What are input IDs?](../glossary#input-ids) + attention_mask (`torch.Tensor` of shape `(batch_size, sequence_length)`, *optional*): + Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`: + + - 1 for tokens that are **not masked**, + - 0 for tokens that are **masked**. + + [What are attention masks?](../glossary#attention-mask) + inputs_embeds (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*): + Optionally, instead of passing `input_ids` you can choose to directly pass an embedded representation. + This is useful if you want more control over how to convert `input_ids` indices into associated vectors + than the model's internal embedding lookup matrix. + output_attentions (`bool`, *optional*): + Whether or not to return the attentions tensors of all attention layers. See `attentions` under + returned tensors for more detail. + output_hidden_states (`bool`, *optional*): + Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors + for more detail. + return_dict (`bool`, *optional*): + Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple. + """ + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + # retrieve input_ids and inputs_embeds + if input_ids is not None and inputs_embeds is not None: + raise ValueError("You cannot specify both input_ids and inputs_embeds at the same time") + elif input_ids is not None: + self.warn_if_padding_and_no_attention_mask(input_ids, attention_mask) + input_shape = input_ids.size() + input_ids = input_ids.view(-1, input_shape[-1]) + elif inputs_embeds is not None: + input_shape = inputs_embeds.size()[:-1] + else: + raise ValueError("You have to specify either input_ids or inputs_embeds") + + if inputs_embeds is None: + inputs_embeds = self.embed_tokens(input_ids) * self.embed_scale + + embed_pos = self.embed_positions(input_shape) + + hidden_states = inputs_embeds + embed_pos + + hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training) + + attention_mask = create_bidirectional_mask( + config=self.config, + inputs_embeds=inputs_embeds, + attention_mask=attention_mask, + ) + + encoder_states = () if output_hidden_states else None + all_attentions = () if output_attentions else None + + for idx, encoder_layer in enumerate(self.layers): + if output_hidden_states: + encoder_states = encoder_states + (hidden_states,) + # add LayerDrop (see https://huggingface.co/papers/1909.11556 for description) + to_drop = False + if self.training: + dropout_probability = torch.rand([]) + if dropout_probability < self.layerdrop: # skip the layer + to_drop = True + + if to_drop: + layer_outputs = (None, None) + else: + layer_outputs = encoder_layer( + hidden_states, + attention_mask, + output_attentions=output_attentions, + ) + + hidden_states = layer_outputs[0] + + if output_attentions: + all_attentions = all_attentions + (layer_outputs[1],) + + hidden_states = self.layer_norm(hidden_states) + + if output_hidden_states: + encoder_states = encoder_states + (hidden_states,) + + if not return_dict: + return tuple(v for v in [hidden_states, encoder_states, all_attentions] if v is not None) + return BaseModelOutput( + last_hidden_state=hidden_states, hidden_states=encoder_states, attentions=all_attentions + ) + + +class PegasusDecoder(PegasusPreTrainedModel): + """ + Transformer decoder consisting of *config.decoder_layers* layers. Each layer is a [`PegasusDecoderLayer`] + + Args: + config: PegasusConfig + embed_tokens (nn.Embedding): output embedding + """ + + def __init__(self, config: PegasusConfig): + super().__init__(config) + self.dropout = config.dropout + self.layerdrop = config.decoder_layerdrop + self.padding_idx = config.pad_token_id + self.max_target_positions = config.max_position_embeddings + self.embed_scale = math.sqrt(config.d_model) if config.scale_embedding else 1.0 + + self.embed_tokens = nn.Embedding(config.vocab_size, config.d_model, self.padding_idx) + + self.embed_positions = PegasusSinusoidalPositionalEmbedding( + config.max_position_embeddings, + config.d_model, + self.padding_idx, + ) + self.layers = nn.ModuleList([PegasusDecoderLayer(config, layer_idx=i) for i in range(config.decoder_layers)]) + self.layer_norm = nn.LayerNorm(config.d_model) + + self.gradient_checkpointing = False + # Initialize weights and apply final processing + self.post_init() + + def resize_position_embeddings(self, new_num_position_embeddings: int): + """ + Resizes position embeddings matrix of the model if `new_num_position_embeddings != + config.max_position_embeddings`. + + Arguments: + new_num_position_embeddings (`int`): + The number of new position embeddings. If position embeddings are learned, increasing the size will add + newly initialized vectors at the end, whereas reducing the size will remove vectors from the end. If + position embeddings are not learned (*e.g.* sinusoidal position embeddings), increasing the size will + add correct vectors at the end following the position encoding algorithm, whereas reducing the size + will remove vectors from the end. + """ + logger.info(f"Setting `config.max_position_embeddings={new_num_position_embeddings}`...") + self.config.max_position_embeddings = new_num_position_embeddings + + self.embed_positions = PegasusSinusoidalPositionalEmbedding( + self.config.max_position_embeddings, + self.config.d_model, + self.padding_idx, + ) + init.copy_(self.embed_positions.weight, self.embed_positions.create_weight()) + self.embed_positions.to(self.device) + + def get_position_embeddings(self) -> nn.Embedding: + """ + Returns the position embeddings matrix + """ + return self.embed_positions + + def forward( + self, + input_ids=None, + attention_mask=None, + encoder_hidden_states=None, + encoder_attention_mask=None, + past_key_values=None, + inputs_embeds=None, + use_cache=None, + output_attentions=None, + output_hidden_states=None, + return_dict=None, + cache_position=None, + **kwargs, + ): + r""" + Args: + input_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`): + Indices of input sequence tokens in the vocabulary. Padding will be ignored by default should you + provide it. + + Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and + [`PreTrainedTokenizer.__call__`] for details. + + [What are input IDs?](../glossary#input-ids) + attention_mask (`torch.Tensor` of shape `(batch_size, sequence_length)`, *optional*): + Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`: + + - 1 for tokens that are **not masked**, + - 0 for tokens that are **masked**. + + [What are attention masks?](../glossary#attention-mask) + encoder_hidden_states (`torch.FloatTensor` of shape `(batch_size, encoder_sequence_length, hidden_size)`, *optional*): + Sequence of hidden-states at the output of the last layer of the encoder. Used in the cross-attention + of the decoder. + encoder_attention_mask (`torch.LongTensor` of shape `(batch_size, encoder_sequence_length)`, *optional*): + Mask to avoid performing cross-attention on padding tokens indices of encoder input_ids. Mask values + selected in `[0, 1]`: + + - 1 for tokens that are **not masked**, + - 0 for tokens that are **masked**. + + [What are attention masks?](../glossary#attention-mask) + past_key_values (`Cache`, *optional*, returned when `use_cache=True` is passed or when `config.use_cache=True`): + It is a [`~cache_utils.Cache`] instance. For more details, see our [kv cache guide](https://huggingface.co/docs/transformers/en/kv_cache). + + Contains pre-computed hidden-states (key and values in the self-attention blocks and in the + cross-attention blocks) that can be used (see `past_key_values` input) to speed up sequential decoding. + + If `past_key_values` are used, the user can optionally input only the last `decoder_input_ids` (those + that don't have their past key value states given to this model) of shape `(batch_size, 1)` instead of + all `decoder_input_ids` of shape `(batch_size, sequence_length)`. + inputs_embeds (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*): + Optionally, instead of passing `input_ids` you can choose to directly pass an embedded representation. + This is useful if you want more control over how to convert `input_ids` indices into associated vectors + than the model's internal embedding lookup matrix. + output_attentions (`bool`, *optional*): + Whether or not to return the attentions tensors of all attention layers. See `attentions` under + returned tensors for more detail. + output_hidden_states (`bool`, *optional*): + Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors + for more detail. + return_dict (`bool`, *optional*): + Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple. + cache_position (`torch.LongTensor` of shape `(sequence_length)`, *optional*): + Indices depicting the position of the input sequence tokens in the sequence. It is used to update the + cache in the correct position and to infer the complete sequence length. + """ + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + use_cache = use_cache if use_cache is not None else self.config.use_cache + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + # retrieve input_ids and inputs_embeds + if (input_ids is None) ^ (inputs_embeds is not None): + raise ValueError("You cannot specify both decoder_input_ids and decoder_inputs_embeds at the same time") + elif input_ids is not None: + input = input_ids + input_shape = input.shape + input_ids = input_ids.view(-1, input_shape[-1]) + elif inputs_embeds is not None: + input_shape = inputs_embeds.size()[:-1] + input = inputs_embeds[:, :, -1] + else: + raise ValueError("You have to specify either decoder_input_ids or decoder_inputs_embeds") + + if inputs_embeds is None: + inputs_embeds = self.embed_tokens(input) + + # important to apply scale outside of `if` in case users pass `embeds` + inputs_embeds = inputs_embeds * self.embed_scale + + if self.gradient_checkpointing and self.training: + if use_cache: + logger.warning_once( + "`use_cache=True` is incompatible with gradient checkpointing`. Setting `use_cache=False`..." + ) + use_cache = False + + # initialize `past_key_values` + if use_cache and past_key_values is None: + past_key_values = ( + EncoderDecoderCache(DynamicCache(config=self.config), DynamicCache(config=self.config)) + if encoder_hidden_states is not None or self.config.is_encoder_decoder + else DynamicCache(config=self.config) + ) + + batch_size, seq_length = inputs_embeds.size()[:-1] + past_key_values_length = past_key_values.get_seq_length() if past_key_values is not None else 0 + if cache_position is None: + cache_position = torch.arange( + past_key_values_length, past_key_values_length + seq_length, device=inputs_embeds.device + ) + + if attention_mask is None and not is_torchdynamo_compiling(): + # required mask seq length can be calculated via length of past cache + mask_seq_length = past_key_values_length + seq_length + attention_mask = torch.ones(batch_size, mask_seq_length, device=inputs_embeds.device) + + self_attn_cache = ( + past_key_values.self_attention_cache + if isinstance(past_key_values, EncoderDecoderCache) + else past_key_values + ) + + causal_mask = create_causal_mask( + config=self.config, + inputs_embeds=inputs_embeds, + attention_mask=attention_mask, + cache_position=cache_position, + past_key_values=self_attn_cache, + ) + encoder_attention_mask = create_bidirectional_mask( + config=self.config, + inputs_embeds=inputs_embeds, + attention_mask=encoder_attention_mask, + encoder_hidden_states=encoder_hidden_states, + ) + + # embed positions + positions = self.embed_positions((batch_size, seq_length), past_key_values_length, position_ids=cache_position) + hidden_states = inputs_embeds + positions + hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training) + + # decoder layers + all_hidden_states = () if output_hidden_states else None + all_self_attns = () if output_attentions else None + all_cross_attentions = () if (output_attentions and encoder_hidden_states is not None) else None + + for idx, decoder_layer in enumerate(self.layers): + # add LayerDrop (see https://huggingface.co/papers/1909.11556 for description) + if output_hidden_states: + all_hidden_states += (hidden_states,) + if self.training: + dropout_probability = torch.rand([]) + if dropout_probability < self.layerdrop: + continue + + layer_outputs = decoder_layer( + hidden_states, + causal_mask, + encoder_hidden_states, # as a positional argument for gradient checkpointing + encoder_attention_mask=encoder_attention_mask, + past_key_values=past_key_values, + output_attentions=output_attentions, + use_cache=use_cache, + cache_position=cache_position, + ) + hidden_states = layer_outputs[0] + + if output_attentions: + all_self_attns += (layer_outputs[1],) + + if encoder_hidden_states is not None: + all_cross_attentions += (layer_outputs[2],) + + hidden_states = self.layer_norm(hidden_states) + + # add hidden states from the last decoder layer + if output_hidden_states: + all_hidden_states += (hidden_states,) + + if not return_dict: + return tuple( + v + for v in [hidden_states, past_key_values, all_hidden_states, all_self_attns, all_cross_attentions] + if v is not None + ) + return BaseModelOutputWithPastAndCrossAttentions( + last_hidden_state=hidden_states, + past_key_values=past_key_values, + hidden_states=all_hidden_states, + attentions=all_self_attns, + cross_attentions=all_cross_attentions, + ) + + +@auto_docstring +class PegasusModel(PegasusPreTrainedModel): + _tied_weights_keys = { + "decoder.embed_tokens.weight": "shared.weight", + "encoder.embed_tokens.weight": "shared.weight", + } + + def __init__(self, config: PegasusConfig): + super().__init__(config) + + padding_idx, vocab_size = config.pad_token_id, config.vocab_size + self.shared = nn.Embedding(vocab_size, config.d_model, padding_idx) + + self.encoder = PegasusEncoder(config) + self.decoder = PegasusDecoder(config) + + # Initialize weights and apply final processing + self.post_init() + + def get_input_embeddings(self): + return self.shared + + def set_input_embeddings(self, value): + self.shared = value + self.encoder.embed_tokens = self.shared + self.decoder.embed_tokens = self.shared + + def resize_position_embeddings(self, new_num_position_embeddings: int): + """ + Resizes position embeddings matrix of the model if `new_num_position_embeddings != + config.max_position_embeddings`. + + Arguments: + new_num_position_embeddings (`int`): + The number of new position embeddings. If position embeddings are learned, increasing the size will add + newly initialized vectors at the end, whereas reducing the size will remove vectors from the end. If + position embeddings are not learned (*e.g.* sinusoidal position embeddings), increasing the size will + add correct vectors at the end following the position encoding algorithm, whereas reducing the size + will remove vectors from the end. + """ + self.config.max_position_embeddings = new_num_position_embeddings + self.encoder.resize_position_embeddings(new_num_position_embeddings) + self.decoder.resize_position_embeddings(new_num_position_embeddings) + + def get_position_embeddings(self) -> tuple[nn.Embedding]: + """ + Returns the position embeddings matrix + """ + return (self.encoder.get_position_embeddings(), self.decoder.get_position_embeddings()) + + @auto_docstring + def forward( + self, + input_ids: torch.Tensor | None = None, + attention_mask: torch.Tensor | None = None, + decoder_input_ids: torch.Tensor | None = None, + decoder_attention_mask: torch.Tensor | None = None, + encoder_outputs: tuple[torch.FloatTensor] | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.Tensor | None = None, + decoder_inputs_embeds: torch.Tensor | None = None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + cache_position: torch.Tensor | None = None, + **kwargs, + ) -> tuple | Seq2SeqModelOutput: + r""" + decoder_input_ids (`torch.LongTensor` of shape `(batch_size, target_sequence_length)`, *optional*): + Indices of decoder input sequence tokens in the vocabulary. + + Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and + [`PreTrainedTokenizer.__call__`] for details. + + [What are decoder input IDs?](../glossary#decoder-input-ids) + + Pegasus uses the `pad_token_id` as the starting token for `decoder_input_ids` generation. If + `past_key_values` is used, optionally only the last `decoder_input_ids` have to be input (see + `past_key_values`). + decoder_attention_mask (`torch.LongTensor` of shape `(batch_size, target_sequence_length)`, *optional*): + Default behavior: generate a tensor that ignores pad tokens in `decoder_input_ids`. Causal mask will also + be used by default. + + Example: + + ```python + >>> from transformers import AutoTokenizer, PegasusModel + + >>> tokenizer = AutoTokenizer.from_pretrained("google/pegasus-large") + >>> model = PegasusModel.from_pretrained("google/pegasus-large") + + >>> inputs = tokenizer("Studies have been shown that owning a dog is good for you", return_tensors="pt") + >>> decoder_inputs = tokenizer("Studies show that", return_tensors="pt") + >>> outputs = model(input_ids=inputs.input_ids, decoder_input_ids=decoder_inputs.input_ids) + + >>> last_hidden_states = outputs.last_hidden_state + >>> list(last_hidden_states.shape) + [1, 4, 1024] + ```""" + + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + use_cache = use_cache if use_cache is not None else self.config.use_cache + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + if encoder_outputs is None: + encoder_outputs = self.encoder( + input_ids=input_ids, + attention_mask=attention_mask, + inputs_embeds=inputs_embeds, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + # If the user passed a tuple for encoder_outputs, we wrap it in a BaseModelOutput when return_dict=True + elif return_dict and not isinstance(encoder_outputs, BaseModelOutput): + encoder_outputs = BaseModelOutput( + last_hidden_state=encoder_outputs[0], + hidden_states=encoder_outputs[1] if len(encoder_outputs) > 1 else None, + attentions=encoder_outputs[2] if len(encoder_outputs) > 2 else None, + ) + + # decoder outputs consists of (dec_features, past_key_values, dec_hidden, dec_attn) + decoder_outputs = self.decoder( + input_ids=decoder_input_ids, + attention_mask=decoder_attention_mask, + encoder_hidden_states=encoder_outputs[0], + encoder_attention_mask=attention_mask, + past_key_values=past_key_values, + inputs_embeds=decoder_inputs_embeds, + use_cache=use_cache, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + cache_position=cache_position, + ) + + if not return_dict: + return decoder_outputs + encoder_outputs + + return Seq2SeqModelOutput( + last_hidden_state=decoder_outputs.last_hidden_state, + past_key_values=decoder_outputs.past_key_values, + decoder_hidden_states=decoder_outputs.hidden_states, + decoder_attentions=decoder_outputs.attentions, + cross_attentions=decoder_outputs.cross_attentions, + encoder_last_hidden_state=encoder_outputs.last_hidden_state, + encoder_hidden_states=encoder_outputs.hidden_states, + encoder_attentions=encoder_outputs.attentions, + ) + + +@auto_docstring( + custom_intro=""" + The PEGASUS Model with a language modeling head. Can be used for summarization. + """ +) +class PegasusForConditionalGeneration(PegasusPreTrainedModel, GenerationMixin): + base_model_prefix = "model" + _keys_to_ignore_on_load_missing = ["final_logits_bias"] + _tied_weights_keys = { + "lm_head.weight": "model.shared.weight", + } + + def __init__(self, config: PegasusConfig): + super().__init__(config) + self.model = PegasusModel(config) + self.register_buffer("final_logits_bias", torch.zeros((1, self.model.shared.num_embeddings))) + self.lm_head = nn.Linear(config.d_model, self.model.shared.num_embeddings, bias=False) + + # Initialize weights and apply final processing + self.post_init() + + def resize_token_embeddings( + self, new_num_tokens: int, pad_to_multiple_of: int | None = None, mean_resizing: bool = True + ) -> nn.Embedding: + new_embeddings = super().resize_token_embeddings(new_num_tokens, pad_to_multiple_of, mean_resizing) + self._resize_final_logits_bias(new_embeddings.weight.shape[0]) + return new_embeddings + + def _resize_final_logits_bias(self, new_num_tokens: int) -> None: + old_num_tokens = self.final_logits_bias.shape[-1] + if new_num_tokens <= old_num_tokens: + new_bias = self.final_logits_bias[:, :new_num_tokens] + else: + extra_bias = torch.zeros((1, new_num_tokens - old_num_tokens), device=self.final_logits_bias.device) + new_bias = torch.cat([self.final_logits_bias, extra_bias], dim=1) + self.register_buffer("final_logits_bias", new_bias) + + def resize_position_embeddings(self, new_num_position_embeddings: int): + """ + Resizes position embeddings matrix of the model if `new_num_position_embeddings != + config.max_position_embeddings`. + + Arguments: + new_num_position_embeddings (`int`): + The number of new position embeddings. If position embeddings are learned, increasing the size will add + newly initialized vectors at the end, whereas reducing the size will remove vectors from the end. If + position embeddings are not learned (*e.g.* sinusoidal position embeddings), increasing the size will + add correct vectors at the end following the position encoding algorithm, whereas reducing the size + will remove vectors from the end. + """ + self.config.max_position_embeddings = new_num_position_embeddings + self.model.encoder.resize_position_embeddings(new_num_position_embeddings) + self.model.decoder.resize_position_embeddings(new_num_position_embeddings) + + def get_position_embeddings(self) -> tuple[nn.Embedding]: + """ + Returns the position embeddings matrix + """ + return (self.model.encoder.get_position_embeddings(), self.model.decoder.get_position_embeddings()) + + @auto_docstring + def forward( + self, + input_ids: torch.Tensor | None = None, + attention_mask: torch.Tensor | None = None, + decoder_input_ids: torch.Tensor | None = None, + decoder_attention_mask: torch.Tensor | None = None, + encoder_outputs: tuple[torch.FloatTensor] | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.Tensor | None = None, + decoder_inputs_embeds: torch.Tensor | None = None, + labels: torch.Tensor | None = None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + cache_position: torch.Tensor | None = None, + **kwargs, + ) -> tuple | Seq2SeqLMOutput: + r""" + decoder_input_ids (`torch.LongTensor` of shape `(batch_size, target_sequence_length)`, *optional*): + Indices of decoder input sequence tokens in the vocabulary. + + Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and + [`PreTrainedTokenizer.__call__`] for details. + + [What are decoder input IDs?](../glossary#decoder-input-ids) + + Pegasus uses the `pad_token_id` as the starting token for `decoder_input_ids` generation. If + `past_key_values` is used, optionally only the last `decoder_input_ids` have to be input (see + `past_key_values`). + decoder_attention_mask (`torch.LongTensor` of shape `(batch_size, target_sequence_length)`, *optional*): + Default behavior: generate a tensor that ignores pad tokens in `decoder_input_ids`. Causal mask will also + be used by default. + labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Labels for computing the masked language modeling loss. Indices should either be in `[0, ..., + config.vocab_size]` or -100 (see `input_ids` docstring). Tokens with indices set to `-100` are ignored + (masked), the loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]`. + + Example Summarization: + + ```python + >>> from transformers import AutoTokenizer, PegasusForConditionalGeneration + + >>> model = PegasusForConditionalGeneration.from_pretrained("google/pegasus-xsum") + >>> tokenizer = AutoTokenizer.from_pretrained("google/pegasus-xsum") + + >>> ARTICLE_TO_SUMMARIZE = ( + ... "PG&E stated it scheduled the blackouts in response to forecasts for high winds " + ... "amid dry conditions. The aim is to reduce the risk of wildfires. Nearly 800 thousand customers were " + ... "scheduled to be affected by the shutoffs which were expected to last through at least midday tomorrow." + ... ) + >>> inputs = tokenizer(ARTICLE_TO_SUMMARIZE, max_length=1024, return_tensors="pt") + + >>> # Generate Summary + >>> summary_ids = model.generate(inputs["input_ids"]) + >>> tokenizer.batch_decode(summary_ids, skip_special_tokens=True, clean_up_tokenization_spaces=False)[0] + "California's largest electricity provider has turned off power to hundreds of thousands of customers." + ``` + """ + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + if labels is not None: + if use_cache: + logger.warning("The `use_cache` argument is changed to `False` since `labels` is provided.") + use_cache = False + if decoder_input_ids is None and decoder_inputs_embeds is None: + decoder_input_ids = shift_tokens_right( + labels, self.config.pad_token_id, self.config.decoder_start_token_id + ) + + outputs = self.model( + input_ids, + attention_mask=attention_mask, + decoder_input_ids=decoder_input_ids, + encoder_outputs=encoder_outputs, + decoder_attention_mask=decoder_attention_mask, + past_key_values=past_key_values, + inputs_embeds=inputs_embeds, + decoder_inputs_embeds=decoder_inputs_embeds, + use_cache=use_cache, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + cache_position=cache_position, + ) + lm_logits = self.lm_head(outputs[0]) + self.final_logits_bias + + masked_lm_loss = None + if labels is not None: + loss_fct = CrossEntropyLoss() + masked_lm_loss = loss_fct(lm_logits.view(-1, self.config.vocab_size), labels.view(-1)) + + if not return_dict: + output = (lm_logits,) + outputs[1:] + return ((masked_lm_loss,) + output) if masked_lm_loss is not None else output + + return Seq2SeqLMOutput( + loss=masked_lm_loss, + logits=lm_logits, + past_key_values=outputs.past_key_values, + decoder_hidden_states=outputs.decoder_hidden_states, + decoder_attentions=outputs.decoder_attentions, + cross_attentions=outputs.cross_attentions, + encoder_last_hidden_state=outputs.encoder_last_hidden_state, + encoder_hidden_states=outputs.encoder_hidden_states, + encoder_attentions=outputs.encoder_attentions, + ) + + def prepare_decoder_input_ids_from_labels(self, labels: torch.Tensor): + return shift_tokens_right(labels, self.config.pad_token_id, self.config.decoder_start_token_id) + + +# Copied from transformers.models.bart.modeling_bart.BartDecoderWrapper with Bart->Pegasus +class PegasusDecoderWrapper(PegasusPreTrainedModel): + """ + This wrapper class is a helper class to correctly load pretrained checkpoints when the causal language model is + used in combination with the [`EncoderDecoderModel`] framework. + """ + + def __init__(self, config): + super().__init__(config) + self.decoder = PegasusDecoder(config) + self.post_init() + + def forward(self, *args, **kwargs): + return self.decoder(*args, **kwargs) + + +class PegasusForCausalLM(PegasusPreTrainedModel, GenerationMixin): + _tied_weights_keys = { + "lm_head.weight": "model.decoder.embed_tokens.weight", + } + + def __init__(self, config): + config = copy.deepcopy(config) + config.is_decoder = True + config.is_encoder_decoder = False + super().__init__(config) + self.model = PegasusDecoderWrapper(config) + + self.lm_head = nn.Linear(config.hidden_size, config.vocab_size, bias=False) + + # Initialize weights and apply final processing + self.post_init() + + def get_input_embeddings(self): + return self.model.decoder.embed_tokens + + def set_input_embeddings(self, value): + self.model.decoder.embed_tokens = value + + def get_position_embeddings(self) -> nn.Embedding: + """ + Returns the position embeddings matrix + """ + return self.model.decoder.get_position_embeddings() + + def resize_position_embeddings(self, new_num_position_embeddings: int): + """ + Resizes position embeddings matrix of the model if `new_num_position_embeddings != + config.max_position_embeddings`. + + Arguments: + new_num_position_embeddings (`int`): + The number of new position embeddings. If position embeddings are learned, increasing the size will add + newly initialized vectors at the end, whereas reducing the size will remove vectors from the end. If + position embeddings are not learned (*e.g.* sinusoidal position embeddings), increasing the size will + add correct vectors at the end following the position encoding algorithm, whereas reducing the size + will remove vectors from the end. + """ + self.config.max_position_embeddings = new_num_position_embeddings + self.model.decoder.resize_position_embeddings(new_num_position_embeddings) + + @auto_docstring + # Copied from transformers.models.bart.modeling_bart.BartForCausalLM.forward with Bart->Pegasus, facebook/bart-base->google/pegasus-large + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.Tensor | None = None, + encoder_hidden_states: torch.FloatTensor | None = None, + encoder_attention_mask: torch.FloatTensor | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.FloatTensor | None = None, + labels: torch.LongTensor | None = None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + cache_position: torch.LongTensor | None = None, + logits_to_keep: int | torch.Tensor = 0, + **kwargs, + ) -> tuple | CausalLMOutputWithCrossAttentions: + r""" + labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Labels for computing the masked language modeling loss. Indices should either be in `[0, ..., + config.vocab_size]` or -100 (see `input_ids` docstring). Tokens with indices set to `-100` are ignored + (masked), the loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]`. + + Example: + + ```python + >>> from transformers import AutoTokenizer, PegasusForCausalLM + + >>> tokenizer = AutoTokenizer.from_pretrained("google/pegasus-large") + >>> model = PegasusForCausalLM.from_pretrained("google/pegasus-large") + >>> assert model.config.is_decoder, f"{model.__class__} has to be configured as a decoder." + >>> inputs = tokenizer("Hello, my dog is cute", return_tensors="pt") + >>> outputs = model(**inputs) + + >>> logits = outputs.logits + >>> expected_shape = [1, inputs.input_ids.shape[-1], model.config.vocab_size] + >>> list(logits.shape) == expected_shape + True + ```""" + + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + # decoder outputs consists of (dec_features, layer_state, dec_hidden, dec_attn) + outputs = self.model.decoder( + input_ids=input_ids, + attention_mask=attention_mask, + encoder_hidden_states=encoder_hidden_states, + encoder_attention_mask=encoder_attention_mask, + past_key_values=past_key_values, + inputs_embeds=inputs_embeds, + use_cache=use_cache, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + cache_position=cache_position, + ) + + hidden_states = outputs[0] + # Only compute necessary logits + slice_indices = slice(-logits_to_keep, None) if isinstance(logits_to_keep, int) else logits_to_keep + logits = self.lm_head(hidden_states[:, slice_indices, :]) + + loss = None + if labels is not None: + labels = labels.to(logits.device) + loss_fct = CrossEntropyLoss() + loss = loss_fct(logits.view(-1, self.config.vocab_size), labels.view(-1)) + + if not return_dict: + output = (logits,) + outputs[1:] + return (loss,) + output if loss is not None else output + + return CausalLMOutputWithCrossAttentions( + loss=loss, + logits=logits, + past_key_values=outputs.past_key_values, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + cross_attentions=outputs.cross_attentions, + ) + + +__all__ = ["PegasusForCausalLM", "PegasusForConditionalGeneration", "PegasusModel", "PegasusPreTrainedModel"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pegasus/tokenization_pegasus.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pegasus/tokenization_pegasus.py new file mode 100644 index 0000000000000000000000000000000000000000..c0ffcf258c60a83c0d4ee26c1254b7d08c9d8433 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pegasus/tokenization_pegasus.py @@ -0,0 +1,133 @@ +# Copyright 2020 Google and The HuggingFace Inc. team. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""Tokenization class for model PEGASUS.""" + +from tokenizers import Regex, Tokenizer, decoders, normalizers, pre_tokenizers, processors +from tokenizers.models import Unigram + +from ...tokenization_utils_tokenizers import TokenizersBackend +from ...utils import logging + + +logger = logging.get_logger(__name__) + +VOCAB_FILES_NAMES = {"vocab_file": "spiece.model", "tokenizer_file": "tokenizer.json"} + + +class PegasusTokenizer(TokenizersBackend): + r""" + Construct a PEGASUS tokenizer (backed by HuggingFace's *tokenizers* library). Based on + [Unigram](https://huggingface.co/docs/tokenizers/python/latest/components.html?highlight=unigram#models). + + This tokenizer inherits from [`TokenizersBackend`] which contains most of the main methods. Users should + refer to this superclass for more information regarding those methods. + + Args: + vocab_file (`str`, *optional*): + [SentencePiece](https://github.com/google/sentencepiece) file (generally has a *.spm* extension) that + contains the vocabulary necessary to instantiate a tokenizer. + pad_token (`str`, *optional*, defaults to `""`): + The token used for padding, for example when batching sequences of different lengths. + eos_token (`str`, *optional*, defaults to `""`): + The end of sequence token. + + + + When building a sequence using special tokens, this is not the token that is used for the end of sequence. + The token used is the `sep_token`. + + + + unk_token (`str`, *optional*, defaults to `""`): + The unknown token. A token that is not in the vocabulary cannot be converted to an ID and is set to be this + token instead. + mask_token (`str`, *optional*, defaults to `""`): + The token used for masking single token values. This is the token used when training this model with masked + language modeling (MLM). This is the token that the PEGASUS encoder will try to predict during pretraining. + It corresponds to *[MASK2]* in [PEGASUS: Pre-training with Extracted Gap-sentences for Abstractive + Summarization](https://huggingface.co/papers/1912.08777). + mask_token_sent (`str`, *optional*, defaults to `""`): + The token used for masking whole target sentences. This is the token used when training this model with gap + sentences generation (GSG). This is the sentence that the PEGASUS decoder will try to predict during + pretraining. It corresponds to *[MASK1]* in [PEGASUS: Pre-training with Extracted Gap-sentences for + Abstractive Summarization](https://huggingface.co/papers/1912.08777). + additional_special_tokens (`List[str]`, *optional*): + Additional special tokens used by the tokenizer. If no additional_special_tokens are provided and + are used as additional special tokens corresponding to the [original PEGASUS + tokenizer](https://github.com/google-research/pegasus/blob/939830367bcf411193d2b5eca2f2f90f3f9260ca/pegasus/ops/pretrain_parsing_ops.cc#L66) + that uses the tokens 2 - 104 only for pretraining + offset (`int`, *optional*, defaults to 103): + Offset for additional special tokens. + vocab (`str` or `list[tuple[str, float]]`, *optional*): + Custom vocabulary with `(token, score)` tuples. If not provided, a blank vocabulary is initialized. + """ + + vocab_files_names = VOCAB_FILES_NAMES + model_input_names = ["input_ids", "attention_mask"] + model = Unigram + + def __init__( + self, + vocab: str | list[tuple[str, float]] | None = None, + pad_token="", + eos_token="", + unk_token="", + mask_token="", + mask_token_sent="", + _spm_precompiled_charsmap=None, + additional_special_tokens=None, + offset=103, + **kwargs, + ): + self.offset = offset + + if additional_special_tokens is None: + additional_special_tokens = [mask_token_sent] if mask_token_sent is not None else [] + additional_special_tokens += [f"" for i in range(2, self.offset)] + + if vocab is None: + vocab = [(str(unk_token), 0.0), (str(pad_token), 0.0), (str(eos_token), 0.0), (str(mask_token), 0.0)] + + self._vocab = vocab + self._tokenizer = Tokenizer(Unigram(vocab=vocab, unk_id=self._vocab.index((str(unk_token), 0.0), 1))) + if _spm_precompiled_charsmap is not None: + self._tokenizer.normalizer = normalizers.Sequence( + [normalizers.Precompiled(_spm_precompiled_charsmap), normalizers.Replace(Regex(r" {2,}"), " ")] + ) + else: + self._tokenizer.normalizer = normalizers.Sequence( + [normalizers.Replace(Regex(r"\n"), " "), normalizers.Replace(Regex(r" {2,}"), " ")] + ) + + self._tokenizer.pre_tokenizer = pre_tokenizers.Metaspace(replacement="▁", prepend_scheme="always", split=True) + self._tokenizer.decoder = decoders.Metaspace(replacement="▁", prepend_scheme="always", split=True) + + super().__init__( + pad_token=pad_token, + eos_token=eos_token, + unk_token=unk_token, + mask_token=mask_token, + mask_token_sent=mask_token_sent, + offset=offset, + additional_special_tokens=additional_special_tokens, + **kwargs, + ) + self._tokenizer.post_processor = processors.TemplateProcessing( + single=f"$A {eos_token}", + pair=f"$A $B {eos_token}", + special_tokens=[(str(eos_token), self.convert_tokens_to_ids(str(eos_token)))], + ) + + +__all__ = ["PegasusTokenizer"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pegasus_x/__init__.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pegasus_x/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..3d362bacf491ea32dcbc89e7b8bba4d9ae1a9261 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pegasus_x/__init__.py @@ -0,0 +1,27 @@ +# Copyright 2024 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from typing import TYPE_CHECKING + +from ...utils import _LazyModule +from ...utils.import_utils import define_import_structure + + +if TYPE_CHECKING: + from .configuration_pegasus_x import * + from .modeling_pegasus_x import * +else: + import sys + + _file = globals()["__file__"] + sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__) diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pegasus_x/configuration_pegasus_x.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pegasus_x/configuration_pegasus_x.py new file mode 100644 index 0000000000000000000000000000000000000000..289a1c43f41d726eda5d6bda9c6162619c5949b5 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pegasus_x/configuration_pegasus_x.py @@ -0,0 +1,170 @@ +# Copyright 2022, Google and The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""PEGASUS-X model configuration""" + +from ...configuration_utils import PreTrainedConfig +from ...utils import logging + + +logger = logging.get_logger(__name__) + + +class PegasusXConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`PegasusXModel`]. It is used to instantiate a + PEGASUS-X model according to the specified arguments, defining the model architecture. Instantiating a + configuration with the defaults will yield a similar configuration to that of the PEGASUS-X + [google/pegasus-x-large](https://huggingface.co/google/pegasus-x-large) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + + Args: + vocab_size (`int`, *optional*, defaults to 96103): + Vocabulary size of the PEGASUS-X model. Defines the number of different tokens that can be represented by + the `inputs_ids` passed when calling [`PegasusXModel`]. + d_model (`int`, *optional*, defaults to 1024): + Dimension of the layers and the pooler layer. + encoder_layers (`int`, *optional*, defaults to 16): + Number of encoder layers. + decoder_layers (`int`, *optional*, defaults to 16): + Number of decoder layers. + encoder_attention_heads (`int`, *optional*, defaults to 16): + Number of attention heads for each attention layer in the Transformer encoder. + decoder_attention_heads (`int`, *optional*, defaults to 16): + Number of attention heads for each attention layer in the Transformer decoder. + decoder_ffn_dim (`int`, *optional*, defaults to 4096): + Dimension of the "intermediate" (often named feed-forward) layer in decoder. + encoder_ffn_dim (`int`, *optional*, defaults to 4096): + Dimension of the "intermediate" (often named feed-forward) layer in decoder. + activation_function (`str` or `function`, *optional*, defaults to `"gelu"`): + The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`, + `"relu"`, `"silu"` and `"gelu_new"` are supported. + dropout (`float`, *optional*, defaults to 0.1): + The dropout probability for all fully connected layers in the embeddings, encoder, and pooler. + attention_dropout (`float`, *optional*, defaults to 0.0): + The dropout ratio for the attention probabilities. + activation_dropout (`float`, *optional*, defaults to 0.0): + The dropout ratio for activations inside the fully connected layer. + max_position_embeddings (`int`, *optional*, defaults to 16384): + The maximum sequence length that this model might ever be used with. Typically set this to something large + just in case (e.g., 512 or 1024 or 2048). + init_std (`float`, *optional*, defaults to 0.02): + The standard deviation of the truncated_normal_initializer for initializing all weight matrices. + encoder_layerdrop (`float`, *optional*, defaults to 0.0): + The LayerDrop probability for the encoder. See the [LayerDrop paper](see https://huggingface.co/papers/1909.11556) + for more details. + decoder_layerdrop (`float`, *optional*, defaults to 0.0): + The LayerDrop probability for the decoder. See the [LayerDrop paper](see https://huggingface.co/papers/1909.11556) + for more details. + use_cache (`bool`, *optional*, defaults to `True`): + Whether or not the model should return the last key/values attentions (not used by all models) + forced_eos_token_id (`int`, *optional*, defaults to 1): + The id of the token to force as the last generated token when `max_length` is reached. Usually set to + `eos_token_id`. + num_global_tokens (`int`, *optional*, defaults to 128): + Number of global tokens to use for the encoder + block_size (`int`, *optional*, defaults to 512): + Block size for encoder local attention. Sequence length should be an exact multiple of block size. + block_size must be a multiple of 2 if stagger_local_block is True + stagger_local_block (`bool`, *optional*, defaults to `True`): + Whether to stagger every other local attention by half a block + + Example: + + ```python + >>> from transformers import PegasusXConfig, PegasusXModel + + >>> # Initializing a PEGASUS google/pegasus-x-large style configuration + >>> configuration = PegasusXConfig() + + >>> # Initializing a model (with random weights) from the google/pegasus-x-large style configuration + >>> model = PegasusXModel(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "pegasus_x" + keys_to_ignore_at_inference = ["past_key_values"] + attribute_map = {"num_attention_heads": "encoder_attention_heads", "hidden_size": "d_model"} + + def __init__( + self, + vocab_size=96103, + max_position_embeddings=16384, + encoder_layers=16, + encoder_ffn_dim=4096, + encoder_attention_heads=16, + decoder_layers=16, + decoder_ffn_dim=4096, + decoder_attention_heads=16, + encoder_layerdrop=0.0, + decoder_layerdrop=0.0, + use_cache=True, + is_encoder_decoder=True, + activation_function="gelu", + d_model=1024, + dropout=0.1, + attention_dropout=0.0, + activation_dropout=0.0, + init_std=0.02, + decoder_start_token_id=0, + scale_embedding=True, + pad_token_id=0, + eos_token_id=1, + forced_eos_token_id=1, + num_global_tokens=32, + block_size=512, + stagger_local_blocks=True, + tie_word_embeddings=True, + **kwargs, + ): + self.vocab_size = vocab_size + self.max_position_embeddings = max_position_embeddings + self.d_model = d_model + self.encoder_ffn_dim = encoder_ffn_dim + self.encoder_layers = encoder_layers + self.encoder_attention_heads = encoder_attention_heads + self.decoder_ffn_dim = decoder_ffn_dim + self.decoder_layers = decoder_layers + self.decoder_attention_heads = decoder_attention_heads + self.dropout = dropout + self.attention_dropout = attention_dropout + self.activation_dropout = activation_dropout + self.activation_function = activation_function + self.init_std = init_std + self.encoder_layerdrop = encoder_layerdrop + self.decoder_layerdrop = decoder_layerdrop + self.use_cache = use_cache + self.num_hidden_layers = encoder_layers + self.scale_embedding = scale_embedding # scale factor will be sqrt(d_model) if True + + self.num_global_tokens = num_global_tokens + self.block_size = block_size + self.stagger_local_blocks = stagger_local_blocks + self.pad_token_id = pad_token_id + self.eos_token_id = eos_token_id + self.decoder_start_token_id = decoder_start_token_id + self.tie_word_embeddings = tie_word_embeddings + + super().__init__( + is_encoder_decoder=is_encoder_decoder, + forced_eos_token_id=forced_eos_token_id, + **kwargs, + ) + + +__all__ = ["PegasusXConfig"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pegasus_x/modeling_pegasus_x.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pegasus_x/modeling_pegasus_x.py new file mode 100644 index 0000000000000000000000000000000000000000..83b4d7054b589380bbc1098229e23975b31e8dac --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pegasus_x/modeling_pegasus_x.py @@ -0,0 +1,1484 @@ +# Copyright 2022, Google and The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""PyTorch PEGASUS-X model.""" + +import math +from collections.abc import Callable +from dataclasses import dataclass + +import numpy as np +import torch +from torch import nn +from torch.nn import CrossEntropyLoss + +from ...activations import ACT2FN +from ...cache_utils import Cache, DynamicCache, EncoderDecoderCache +from ...generation import GenerationMixin +from ...masking_utils import create_bidirectional_mask, create_causal_mask +from ...modeling_flash_attention_utils import FlashAttentionKwargs +from ...modeling_layers import GradientCheckpointingLayer +from ...modeling_outputs import ( + BaseModelOutput, + BaseModelOutputWithPastAndCrossAttentions, + Seq2SeqLMOutput, + Seq2SeqModelOutput, +) +from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel +from ...processing_utils import Unpack +from ...utils import TransformersKwargs, auto_docstring, is_torchdynamo_compiling, logging +from ...utils.deprecation import deprecate_kwarg +from .configuration_pegasus_x import PegasusXConfig + + +logger = logging.get_logger(__name__) + + +@dataclass +class DimensionInfo: + """Wrapper for dimension info.""" + + batch_size: int # batch size + seq_len: int # token length + block_size: int # block size + num_heads: int # num heads + hidden_dim: int # hidden dim + dim_per_head: int # dim per head + num_blocks: int # num blocks + global_len: int # global length + padded_seq_len: int # padded token seq length + + +# Copied from transformers.models.bart.modeling_bart.shift_tokens_right +def shift_tokens_right(input_ids: torch.Tensor, pad_token_id: int, decoder_start_token_id: int): + """ + Shift input ids one token to the right. + """ + shifted_input_ids = input_ids.new_zeros(input_ids.shape) + shifted_input_ids[:, 1:] = input_ids[:, :-1].clone() + shifted_input_ids[:, 0] = decoder_start_token_id + + if pad_token_id is None: + raise ValueError("self.model.config.pad_token_id has to be defined.") + # replace possible -100 values in labels by `pad_token_id` + shifted_input_ids.masked_fill_(shifted_input_ids == -100, pad_token_id) + + return shifted_input_ids + + +# Copied from transformers.models.bart.modeling_bart.BartScaledWordEmbedding with Bart->PegasusX +class PegasusXScaledWordEmbedding(nn.Embedding): + """ + This module overrides nn.Embeddings' forward by multiplying with embeddings scale. + """ + + def __init__(self, num_embeddings: int, embedding_dim: int, padding_idx: int, embed_scale: float | None = 1.0): + super().__init__(num_embeddings, embedding_dim, padding_idx) + self.embed_scale = embed_scale + + def forward(self, input_ids: torch.Tensor): + return super().forward(input_ids) * self.embed_scale + + +class PegasusXSinusoidalPositionalEmbedding(nn.Module): + """This module produces sinusoidal positional embeddings of any length.""" + + def __init__(self, embed_dim, max_scale: int = 10000.0): + super().__init__() + self.embed_dim = embed_dim + self.max_scale = max_scale + + @deprecate_kwarg("input_embeds", version="5.6.0", new_name="inputs_embeds") + @torch.no_grad() + def forward( + self, inputs_embeds: torch.Tensor, past_key_values_length: int = 0, position_ids: torch.Tensor | None = None + ) -> torch.Tensor: + """`input_ids_shape` is expected to be [bsz x seqlen].""" + batch_size, seq_len = inputs_embeds.shape[:2] + if position_ids is None: + position_ids = torch.arange( + past_key_values_length, past_key_values_length + seq_len, dtype=torch.long, device=inputs_embeds.device + )[:, None] + + pe = torch.zeros((seq_len, self.embed_dim), device=inputs_embeds.device, dtype=inputs_embeds.dtype) + half_d_feature = self.embed_dim // 2 + div_term = torch.exp( + torch.arange(half_d_feature, device=inputs_embeds.device, dtype=torch.int64).type_as(inputs_embeds) + * -(np.log(float(self.max_scale)) / (half_d_feature - 1)) + ) + pe[:, :half_d_feature] = torch.sin(position_ids * div_term) + pe[:, half_d_feature:] = torch.cos(position_ids * div_term) + return pe[None].expand(batch_size, -1, -1) + + +# Copied from transformers.models.bert.modeling_bert.eager_attention_forward +def eager_attention_forward( + module: nn.Module, + query: torch.Tensor, + key: torch.Tensor, + value: torch.Tensor, + attention_mask: torch.Tensor | None, + scaling: float | None = None, + dropout: float = 0.0, + **kwargs: Unpack[TransformersKwargs], +): + if scaling is None: + scaling = query.size(-1) ** -0.5 + + # Take the dot product between "query" and "key" to get the raw attention scores. + attn_weights = torch.matmul(query, key.transpose(2, 3)) * scaling + + if attention_mask is not None: + attn_weights = attn_weights + attention_mask + + attn_weights = nn.functional.softmax(attn_weights, dim=-1) + attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training) + + attn_output = torch.matmul(attn_weights, value) + attn_output = attn_output.transpose(1, 2).contiguous() + + return attn_output, attn_weights + + +# Copied from transformers.models.bart.modeling_bart.BartAttention with Bart->PegasusX +class PegasusXAttention(nn.Module): + """Multi-headed attention from 'Attention Is All You Need' paper""" + + def __init__( + self, + embed_dim: int, + num_heads: int, + dropout: float = 0.0, + is_decoder: bool = False, + bias: bool = True, + is_causal: bool = False, + config: PegasusXConfig | None = None, + layer_idx: int | None = None, + ): + super().__init__() + self.embed_dim = embed_dim + self.num_heads = num_heads + self.dropout = dropout + self.head_dim = embed_dim // num_heads + self.config = config + + if (self.head_dim * num_heads) != self.embed_dim: + raise ValueError( + f"embed_dim must be divisible by num_heads (got `embed_dim`: {self.embed_dim}" + f" and `num_heads`: {num_heads})." + ) + self.scaling = self.head_dim**-0.5 + self.is_decoder = is_decoder + self.is_causal = is_causal + self.layer_idx = layer_idx + if layer_idx is None and self.is_decoder: + logger.warning_once( + f"Instantiating a decoder {self.__class__.__name__} without passing `layer_idx` is not recommended and " + "will lead to errors during the forward call, if caching is used. Please make sure to provide a `layer_idx` " + "when creating this class." + ) + + self.k_proj = nn.Linear(embed_dim, embed_dim, bias=bias) + self.v_proj = nn.Linear(embed_dim, embed_dim, bias=bias) + self.q_proj = nn.Linear(embed_dim, embed_dim, bias=bias) + self.out_proj = nn.Linear(embed_dim, embed_dim, bias=bias) + + def forward( + self, + hidden_states: torch.Tensor, + key_value_states: torch.Tensor | None = None, + past_key_values: Cache | None = None, + attention_mask: torch.Tensor | None = None, + output_attentions: bool = False, + cache_position: torch.Tensor | None = None, + # TODO: we need a refactor so that the different attention modules can get their specific kwargs + # ATM, we have mixed things encoder, decoder, and encoder-decoder attn + **kwargs: Unpack[FlashAttentionKwargs], + ) -> tuple[torch.Tensor, torch.Tensor | None, tuple[torch.Tensor] | None]: + """Input shape: Batch x Time x Channel""" + + # if key_value_states are provided this layer is used as a cross-attention layer + # for the decoder + is_cross_attention = key_value_states is not None + + # determine input shapes + bsz, tgt_len = hidden_states.shape[:-1] + src_len = key_value_states.shape[1] if is_cross_attention else tgt_len + + q_input_shape = (bsz, tgt_len, -1, self.head_dim) + kv_input_shape = (bsz, src_len, -1, self.head_dim) + + # get query proj + query_states = self.q_proj(hidden_states).view(*q_input_shape).transpose(1, 2) + + is_updated = False + if past_key_values is not None: + if isinstance(past_key_values, EncoderDecoderCache): + is_updated = past_key_values.is_updated.get(self.layer_idx) + if is_cross_attention: + # after the first generated id, we can subsequently re-use all key/value_states from cache + curr_past_key_values = past_key_values.cross_attention_cache + else: + curr_past_key_values = past_key_values.self_attention_cache + else: + curr_past_key_values = past_key_values + + current_states = key_value_states if is_cross_attention else hidden_states + if is_cross_attention and past_key_values is not None and is_updated: + # reuse k,v, cross_attentions + key_states = curr_past_key_values.layers[self.layer_idx].keys + value_states = curr_past_key_values.layers[self.layer_idx].values + else: + key_states = self.k_proj(current_states) + value_states = self.v_proj(current_states) + key_states = key_states.view(*kv_input_shape).transpose(1, 2) + value_states = value_states.view(*kv_input_shape).transpose(1, 2) + + if past_key_values is not None: + # save all key/value_states to cache to be re-used for fast auto-regressive generation + cache_position = cache_position if not is_cross_attention else None + key_states, value_states = curr_past_key_values.update( + key_states, value_states, self.layer_idx, {"cache_position": cache_position} + ) + # set flag that curr layer for cross-attn is already updated so we can re-use in subsequent calls + if is_cross_attention and isinstance(past_key_values, EncoderDecoderCache): + past_key_values.is_updated[self.layer_idx] = True + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, eager_attention_forward + ) + + attn_output, attn_weights = attention_interface( + self, + query_states, + key_states, + value_states, + attention_mask, + dropout=0.0 if not self.training else self.dropout, + scaling=self.scaling, + output_attentions=output_attentions, + **kwargs, + ) + + attn_output = attn_output.reshape(bsz, tgt_len, -1).contiguous() + attn_output = self.out_proj(attn_output) + + return attn_output, attn_weights + + +class PegasusXGlobalLocalAttention(nn.Module): + """Global + Local attention. For use with Encoder only.""" + + def __init__( + self, + embed_dim: int, + num_heads: int, + block_size: int, + dropout: float = 0.0, + is_decoder: bool = False, + ): + super().__init__() + self.embed_dim = embed_dim + self.num_heads = num_heads + self.block_size = block_size + self.dropout = dropout + self.head_dim = embed_dim // num_heads + + if (self.head_dim * num_heads) != self.embed_dim: + raise ValueError( + f"embed_dim must be divisible by num_heads (got `embed_dim`: {self.embed_dim}" + f" and `num_heads`: {num_heads})." + ) + self.scaling = self.head_dim**-0.5 + self.is_decoder = is_decoder + + self.k_proj = nn.Linear(embed_dim, embed_dim, bias=False) + self.v_proj = nn.Linear(embed_dim, embed_dim, bias=False) + self.q_proj = nn.Linear(embed_dim, embed_dim, bias=False) + self.out_proj = nn.Linear(embed_dim, embed_dim, bias=False) + + def _shape(self, tensor: torch.Tensor, seq_len: int, bsz: int): + return tensor.view(bsz, seq_len, self.num_heads, self.head_dim).transpose(1, 2).contiguous() + + def forward( + self, + token_hidden_states: torch.Tensor, + global_hidden_states: torch.Tensor, + attention_mask: torch.Tensor | None = None, + output_attentions: bool = False, + ) -> tuple[torch.Tensor, torch.Tensor, torch.Tensor | None]: + """Input shape: Batch x Time x Channel""" + dim = DimensionInfo( + batch_size=token_hidden_states.shape[0], + seq_len=token_hidden_states.shape[1], + block_size=self.block_size, + num_heads=self.num_heads, + hidden_dim=token_hidden_states.shape[2], + dim_per_head=self.head_dim, + num_blocks=token_hidden_states.shape[1] // self.block_size, + global_len=global_hidden_states.shape[1], + padded_seq_len=token_hidden_states.shape[1], + ) + + # [batch_size, num_heads, padded_seq_len, dim_per_head] + local_q = self._shape( + self.q_proj(token_hidden_states) * self.scaling, + seq_len=dim.padded_seq_len, + bsz=dim.batch_size, + ) + local_k = self._shape( + self.k_proj(token_hidden_states), + seq_len=dim.padded_seq_len, + bsz=dim.batch_size, + ) + local_v = self._shape( + self.v_proj(token_hidden_states), + seq_len=dim.padded_seq_len, + bsz=dim.batch_size, + ) + + # [batch_size, num_heads, global_len, dim_per_head] + global_q = self._shape( + self.q_proj(global_hidden_states) * self.scaling, + seq_len=dim.global_len, + bsz=dim.batch_size, + ) + global_k = self._shape( + self.k_proj(global_hidden_states), + seq_len=dim.global_len, + bsz=dim.batch_size, + ) + global_v = self._shape( + self.v_proj(global_hidden_states), + seq_len=dim.global_len, + bsz=dim.batch_size, + ) + + global_attn_output, global_attn_probs = self.compute_global_attention_representations( + global_q=global_q, + global_k=global_k, + global_v=global_v, + local_k=local_k, + local_v=local_v, + mask=attention_mask, + dim=dim, + ) + local_attn_output, local_attn_probs = self.compute_local_attention_representations( + global_k=global_k, + global_v=global_v, + local_q=local_q, + local_k=local_k, + local_v=local_v, + mask=attention_mask, + dim=dim, + ) + + # [batch_size, global_len, hidden_dim] + global_attn_output = ( + global_attn_output.transpose(1, 2).contiguous().view(dim.batch_size, dim.global_len, dim.hidden_dim) + ) + # [batch_size, global_len, hidden_dim] + global_attn_output = self.out_proj(global_attn_output) + # [batch_size, num_heads, block_size, num_heads, dim_per_head] + local_attn_output = local_attn_output.permute(0, 2, 3, 1, 4).contiguous() + # [batch_size, padded_seq_len, hidden_dim] + local_attn_output = local_attn_output.view(dim.batch_size, dim.padded_seq_len, dim.hidden_dim) + # [batch_size, padded_seq_len, hidden_dim] + local_attn_output = self.out_proj(local_attn_output) + + if output_attentions: + attn_probs = {"global": global_attn_probs, "local": local_attn_probs} + else: + attn_probs = None + + return local_attn_output, global_attn_output, attn_probs + + def compute_global_attention_representations( + self, global_q, global_k, global_v, local_k, local_v, mask, dim: DimensionInfo + ): + """Compute attention representations for global tokens. + + Global tokens will attend to both global tokens as well as all input sequence tokens. Because the input + sequence tokens are arranged in blocks for local attention, we unblock them and compute attention. + + Args: + global_q (`torch.FloatTensor`) of shape [batch_size, num_heads, global_len, dim_per_head]: + query vectors from global tokens + global_k (`torch.FloatTensor`) of shape [batch_size, num_heads, global_len, dim_per_head]: + key vectors from global tokens + global_v (`torch.FloatTensor`) of shape [batch_size, num_heads, global_len, dim_per_head]: + value vectors from global tokens + local_k (`torch.FloatTensor`) of shape [batch_size, num_heads, padded_seq_len, dim_per_head]: + key vectors from local tokens + local_v (`torch.FloatTensor`) of shape [batch_size, num_heads, padded_seq_len, dim_per_head]: + value vectors from local tokens + mask (`torch.FloatTensor`) of shape [batch_size, padded_seq_len]: attention mask + dim (DimensionInfo): DimensionInfo wrapper for dimensions + + Returns: + output of shape `[batch_sizes, length, features]`. where length will be padded to a multiple of block_size + """ + # [batch_size, num_heads, global_len+padded_seq_len, dim_per_head] + global_and_local_k = torch.cat([global_k, local_k], dim=2) + # [batch_size, num_heads, global_len+padded_seq_len, dim_per_head] + global_and_local_v = torch.cat([global_v, local_v], dim=2) + + # [batch_size, global_len+padded_seq_len] + extended_mask = nn.functional.pad(mask, pad=(dim.global_len, 0), value=0) + + # [batch_size, num_heads, global_len, global_len+padded_seq_len] + attn_weights = torch.einsum("BHGF,BHXF->BHGX", global_q, global_and_local_k) + attn_weights = attn_weights + extended_mask[:, None, None, :] + attn_probs = nn.functional.softmax(attn_weights, dim=-1) + attn_probs = nn.functional.dropout(attn_probs, p=self.dropout, training=self.training) + + # [batch_size, num_heads, global_len, F] + attn_output = torch.einsum("BHGX,BHXF->BHGF", attn_probs, global_and_local_v) + return attn_output, attn_probs + + def compute_local_attention_representations( + self, global_k, global_v, local_q, local_k, local_v, mask, dim: DimensionInfo + ): + """Compute attention representations for local tokens. + + Local tokens will attend to both global tokens as well as all other tokens within the same local block. Hence, + we need to tile and concatenate the global tokens to every local block + + Args: + global_k (`torch.FloatTensor`) of shape [batch_size, num_heads, global_len, dim_per_head]: + key vectors from global tokens + global_v (`torch.FloatTensor`) of shape [batch_size, num_heads, global_len, dim_per_head]: + value vectors from global tokens + local_q (`torch.FloatTensor`) of shape [batch_size, num_heads, padded_seq_len, dim_per_head]: + query vectors from local tokens + local_k (`torch.FloatTensor`) of shape [batch_size, num_heads, padded_seq_len, dim_per_head]: + key vectors from local tokens + local_v (`torch.FloatTensor`) of shape [batch_size, num_heads, padded_seq_len, dim_per_head]: + value vectors from local tokens + mask (`torch.FloatTensor`) of shape [batch_size, padded_seq_len]: attention mask + dim (DimensionInfo): DimensionInfo wrapper for dimensions + + Returns: + output of shape `[batch_sizes, length, features]`. where length will be padded to a multiple of block_size + """ + # [batch_size, num_heads, num_blocks, block_size, dim_per_head] + blocked_local_q = local_q.view(dim.batch_size, dim.num_heads, dim.num_blocks, dim.block_size, dim.dim_per_head) + # [batch_size, num_heads, num_blocks, block_size, dim_per_head] + blocked_local_k = local_k.view(dim.batch_size, dim.num_heads, dim.num_blocks, dim.block_size, dim.dim_per_head) + # [batch_size, num_heads, num_blocks, block_size, dim_per_head] + blocked_local_v = local_v.view(dim.batch_size, dim.num_heads, dim.num_blocks, dim.block_size, dim.dim_per_head) + + # [batch_size, num_blocks, global_len+block_size] + extended_mask = nn.functional.pad( + mask.view(dim.batch_size, dim.num_blocks, dim.block_size), + pad=(dim.global_len, 0), + value=0, + ) + + # [batch_size, num_heads, num_blocks, block_size, global_len] + blocked_local2global = torch.einsum("BHNKF,BHGF->BHNKG", blocked_local_q, global_k) + # [batch_size, num_heads, num_blocks, block_size, block_size] + blocked_local2local = torch.einsum("BHNKF,BHNXF->BHNKX", blocked_local_q, blocked_local_k) + + # [batch_size, num_heads, num_blocks, block_size, global_len+block_size] + attn_weights = torch.cat([blocked_local2global, blocked_local2local], dim=-1) + attn_weights = attn_weights + extended_mask[:, None, :, None, :] + attn_probs = nn.functional.softmax(attn_weights, dim=-1) + attn_probs = nn.functional.dropout(attn_probs, p=self.dropout, training=self.training) + + # [batch_size, num_heads, num_blocks, block_size, global_len] + local2global_attn_probs = attn_probs[:, :, :, :, : dim.global_len] + # [batch_size, num_heads, num_blocks, block_size, block_size] + local2local_attn_probs = attn_probs[:, :, :, :, dim.global_len :] + + # [batch_size, num_heads, num_blocks, block_size, dim_per_head] + local2global_attn_output = torch.einsum("BHNKG,BHGF->BHNKF", local2global_attn_probs, global_v) + # [batch_size, num_heads, num_blocks, block_size, dim_per_head] + local2local_attn_output = torch.einsum("BHNKX,BHNXF->BHNKF", local2local_attn_probs, blocked_local_v) + # [batch_size, num_heads, num_blocks, block_size, dim_per_head] + attn_output = local2global_attn_output + local2local_attn_output + return attn_output, attn_probs + + +class PegasusXEncoderLayer(GradientCheckpointingLayer): + def __init__(self, stagger_blocks_this_layer: bool, config: PegasusXConfig): + super().__init__() + self.embed_dim = config.d_model + self.self_attn = PegasusXGlobalLocalAttention( + embed_dim=self.embed_dim, + num_heads=config.encoder_attention_heads, + block_size=config.block_size, + dropout=config.attention_dropout, + ) + self.self_attn_layer_norm = nn.LayerNorm(self.embed_dim) + self.global_self_attn_layer_norm = nn.LayerNorm(self.embed_dim) + self.dropout = config.dropout + self.activation_fn = ACT2FN[config.activation_function] + self.activation_dropout = config.activation_dropout + self.fc1 = nn.Linear(self.embed_dim, config.encoder_ffn_dim) + self.fc2 = nn.Linear(config.encoder_ffn_dim, self.embed_dim) + self.final_layer_norm = nn.LayerNorm(self.embed_dim) + self.stagger_blocks_this_layer = stagger_blocks_this_layer + self.block_size = config.block_size + + def forward( + self, + hidden_states: torch.Tensor, + global_hidden_states: torch.Tensor, + attention_mask: torch.Tensor, + output_attentions: bool = False, + ) -> torch.Tensor: + """ + Args: + hidden_states (`torch.FloatTensor`): input to the layer of shape *(seq_len, batch, embed_dim)* + global_hidden_states (`torch.FloatTensor`): global token hidden states + *(seq_len, num_global_tokens, embed_dim)* + attention_mask (`torch.FloatTensor`): attention mask of size + *(batch, 1, tgt_len, src_len)* where padding elements are indicated by very large negative values. + output_attentions (`bool`, *optional*): + Whether or not to return the attentions tensors of all attention layers. See `attentions` under + returned tensors for more detail. + """ + residual = hidden_states + global_residual = global_hidden_states + + hidden_states = self.self_attn_layer_norm(hidden_states) + global_hidden_states = self.global_self_attn_layer_norm(global_hidden_states) + + if self.stagger_blocks_this_layer: + # Pad the blocks to simulate staggering + hidden_states, attention_mask = self.pad_local_tokens( + hidden_states=hidden_states, attention_mask=attention_mask, block_size=self.block_size + ) + + hidden_states, global_hidden_states, attn_weights = self.self_attn( + token_hidden_states=hidden_states, + global_hidden_states=global_hidden_states, + attention_mask=attention_mask, + output_attentions=output_attentions, + ) + + if self.stagger_blocks_this_layer: + # Undo the padding + hidden_states = self.unpad_local_tokens(padded_hidden_states=hidden_states, block_size=self.block_size) + + hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training) + hidden_states = residual + hidden_states + + global_hidden_states = nn.functional.dropout(global_hidden_states, p=self.dropout, training=self.training) + global_hidden_states = global_residual + global_hidden_states + + residual = hidden_states + hidden_states = self.final_layer_norm(hidden_states) + hidden_states = self.activation_fn(self.fc1(hidden_states)) + hidden_states = nn.functional.dropout(hidden_states, p=self.activation_dropout, training=self.training) + hidden_states = self.fc2(hidden_states) + hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training) + hidden_states = residual + hidden_states + + global_residual = global_hidden_states + global_hidden_states = self.final_layer_norm(global_hidden_states) + global_hidden_states = self.activation_fn(self.fc1(global_hidden_states)) + global_hidden_states = nn.functional.dropout( + global_hidden_states, p=self.activation_dropout, training=self.training + ) + global_hidden_states = self.fc2(global_hidden_states) + global_hidden_states = nn.functional.dropout(global_hidden_states, p=self.dropout, training=self.training) + global_hidden_states = global_residual + global_hidden_states + outputs = (hidden_states, global_hidden_states) + + if output_attentions: + outputs += (attn_weights,) + + return outputs + + @classmethod + def pad_local_tokens(cls, hidden_states, attention_mask, block_size): + # hidden_states: [batch_size, seq_len, hidden_dim] + pad_size = block_size // 2 + mask_min_value = torch.finfo(hidden_states.dtype).min + padded_hidden_states = torch.nn.functional.pad( + hidden_states, + pad=(0, 0, pad_size, pad_size), + ) + padded_mask = torch.nn.functional.pad( + attention_mask, + pad=(pad_size, pad_size), + value=mask_min_value, + ) + return padded_hidden_states, padded_mask + + @classmethod + def unpad_local_tokens(cls, padded_hidden_states, block_size): + # padded_hidden_states: [batch_size, padded seq_len, hidden_dim] + pad_size = block_size // 2 + return padded_hidden_states[:, pad_size:-pad_size, :] + + +class PegasusXDecoderLayer(GradientCheckpointingLayer): + def __init__(self, config: PegasusXConfig, layer_idx: int | None = None): + super().__init__() + self.embed_dim = config.d_model + + self.self_attn = PegasusXAttention( + embed_dim=self.embed_dim, + num_heads=config.decoder_attention_heads, + dropout=config.attention_dropout, + is_decoder=True, + bias=False, + config=config, + layer_idx=layer_idx, + ) + self.dropout = config.dropout + self.activation_fn = ACT2FN[config.activation_function] + self.activation_dropout = config.activation_dropout + + self.self_attn_layer_norm = nn.LayerNorm(self.embed_dim) + self.encoder_attn = PegasusXAttention( + self.embed_dim, + config.decoder_attention_heads, + dropout=config.attention_dropout, + is_decoder=True, + bias=False, + config=config, + layer_idx=layer_idx, + ) + self.encoder_attn_layer_norm = nn.LayerNorm(self.embed_dim) + self.fc1 = nn.Linear(self.embed_dim, config.decoder_ffn_dim) + self.fc2 = nn.Linear(config.decoder_ffn_dim, self.embed_dim) + self.final_layer_norm = nn.LayerNorm(self.embed_dim) + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.Tensor | None = None, + encoder_hidden_states: torch.Tensor | None = None, + encoder_attention_mask: torch.Tensor | None = None, + past_key_values: Cache | None = None, + output_attentions: bool | None = False, + use_cache: bool | None = True, + cache_position: torch.Tensor | None = None, + ) -> torch.Tensor: + """ + Args: + hidden_states (`torch.FloatTensor`): input to the layer of shape *(seq_len, batch, embed_dim)* + attention_mask (`torch.FloatTensor`): attention mask of size + *(batch, 1, tgt_len, src_len)* where padding elements are indicated by very large negative values. + encoder_hidden_states (`torch.FloatTensor`): + cross attention input to the layer of shape *(seq_len, batch, embed_dim)* + encoder_attention_mask (`torch.FloatTensor`): encoder attention mask of size + *(batch, 1, tgt_len, src_len)* where padding elements are indicated by very large negative values. + past_key_values (`Cache`): cached past key and value projection states + output_attentions (`bool`, *optional*): + Whether or not to return the attentions tensors of all attention layers. See `attentions` under + returned tensors for more detail. + use_cache: Whether to us KV cache for decoding + cache_position (`torch.LongTensor` of shape `(sequence_length)`, *optional*): + Indices depicting the position of the input sequence tokens in the sequence. It is used to update the + cache in the correct position and to infer the complete sequence length. + """ + residual = hidden_states + hidden_states = self.self_attn_layer_norm(hidden_states) + + # Self Attention + hidden_states, self_attn_weights = self.self_attn( + hidden_states=hidden_states, + past_key_values=past_key_values, + attention_mask=attention_mask, + output_attentions=output_attentions, + cache_position=cache_position, + ) + hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training) + hidden_states = residual + hidden_states + + # Cross-Attention Block + cross_attn_weights = None + if encoder_hidden_states is not None: + residual = hidden_states + hidden_states = self.encoder_attn_layer_norm(hidden_states) + + hidden_states, cross_attn_weights = self.encoder_attn( + hidden_states=hidden_states, + key_value_states=encoder_hidden_states, + attention_mask=encoder_attention_mask, + past_key_values=past_key_values, + output_attentions=output_attentions, + ) + hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training) + hidden_states = residual + hidden_states + + # Fully Connected + residual = hidden_states + hidden_states = self.final_layer_norm(hidden_states) + hidden_states = self.activation_fn(self.fc1(hidden_states)) + hidden_states = nn.functional.dropout(hidden_states, p=self.activation_dropout, training=self.training) + hidden_states = self.fc2(hidden_states) + hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training) + hidden_states = residual + hidden_states + + outputs = (hidden_states,) + + if output_attentions: + outputs += (self_attn_weights, cross_attn_weights) + return outputs + + +@auto_docstring +class PegasusXPreTrainedModel(PreTrainedModel): + config: PegasusXConfig + base_model_prefix = "model" + supports_gradient_checkpointing = True + _no_split_modules = [r"PegasusXEncoderLayer", r"PegasusXDecoderLayer"] + _supports_flash_attn = True + # Flaky logits + _supports_sdpa = False + _supports_flex_attn = True + _can_compile_fullgraph = True + + +class PegasusXEncoder(PegasusXPreTrainedModel): + """ + Transformer encoder consisting of *config.encoder_layers* self attention layers. Each layer is a + [`PegasusXEncoderLayer`]. + + Args: + config: PegasusXConfig + embed_tokens (nn.Embedding): output embedding + """ + + def __init__(self, config: PegasusXConfig): + super().__init__(config) + + self.dropout = config.dropout + self.layerdrop = config.encoder_layerdrop + + embed_dim = config.d_model + padding_idx = config.pad_token_id + self.max_source_positions = config.max_position_embeddings + embed_scale = math.sqrt(embed_dim) if config.scale_embedding else 1.0 + + self.embed_tokens = PegasusXScaledWordEmbedding( + config.vocab_size, embed_dim, padding_idx, embed_scale=embed_scale + ) + + self.embed_global = nn.Embedding(config.num_global_tokens, embed_dim) + self.embed_positions = PegasusXSinusoidalPositionalEmbedding(embed_dim) + self.layers = nn.ModuleList( + [ + PegasusXEncoderLayer( + stagger_blocks_this_layer=i % 2 == 1 and config.stagger_local_blocks, config=config + ) + for i in range(config.encoder_layers) + ] + ) + self.layer_norm = nn.LayerNorm(config.d_model) + + self.gradient_checkpointing = False + # Initialize weights and apply final processing + self.post_init() + + def resize_position_embeddings(self, new_num_position_embeddings: int): + """ + Resizes position embeddings matrix of the model if `new_num_position_embeddings != + config.max_position_embeddings`. + + Arguments: + new_num_position_embeddings (`int`): + The number of new position embeddings. If position embeddings are learned, increasing the size will add + newly initialized vectors at the end, whereas reducing the size will remove vectors from the end. If + position embeddings are not learned (*e.g.* sinusoidal position embeddings), increasing the size will + add correct vectors at the end following the position encoding algorithm, whereas reducing the size + will remove vectors from the end. + """ + logger.info(f"Setting `config.max_position_embeddings={new_num_position_embeddings}`...") + self.config.max_position_embeddings = new_num_position_embeddings + + self.embed_positions = PegasusXSinusoidalPositionalEmbedding(self.config.d_model) + self.embed_positions.to(self.device) + + def get_position_embeddings(self) -> nn.Embedding: + """ + Returns the position embeddings matrix + """ + return self.embed_positions + + def forward( + self, + input_ids=None, + attention_mask=None, + inputs_embeds=None, + output_attentions=None, + output_hidden_states=None, + return_dict=None, + **kwargs, + ): + r""" + Args: + input_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`): + Indices of input sequence tokens in the vocabulary. Padding will be ignored by default should you + provide it. + + Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and + [`PreTrainedTokenizer.__call__`] for details. + + [What are input IDs?](../glossary#input-ids) + attention_mask (`torch.Tensor` of shape `(batch_size, sequence_length)`, *optional*): + Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`: + + - 1 for tokens that are **not masked**, + - 0 for tokens that are **masked**. + + [What are attention masks?](../glossary#attention-mask) + + inputs_embeds (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*): + Optionally, instead of passing `input_ids` you can choose to directly pass an embedded representation. + This is useful if you want more control over how to convert `input_ids` indices into associated vectors + than the model's internal embedding lookup matrix. + output_attentions (`bool`, *optional*): + Whether or not to return the attentions tensors of all attention layers. See `attentions` under + returned tensors for more detail. + output_hidden_states (`bool`, *optional*): + Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors + for more detail. + return_dict (`bool`, *optional*): + Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple. + """ + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + # retrieve input_ids and inputs_embeds + if input_ids is not None and inputs_embeds is not None: + raise ValueError("You cannot specify both input_ids and inputs_embeds at the same time") + elif input_ids is not None: + self.warn_if_padding_and_no_attention_mask(input_ids, attention_mask) + input_shape = input_ids.size() + input_ids = input_ids.view(-1, input_shape[-1]) + elif inputs_embeds is not None: + input_shape = inputs_embeds.size()[:-1] + else: + raise ValueError("You have to specify either input_ids or inputs_embeds") + + if inputs_embeds is None: + inputs_embeds = self.embed_tokens(input_ids) + + embed_pos = self.embed_positions(inputs_embeds) + + hidden_states = inputs_embeds + embed_pos + hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training) + + batch_size, seq_len, _ = hidden_states.shape + + # Setup mask + if attention_mask is None: + attention_mask = torch.ones(*input_shape, dtype=inputs_embeds.dtype, device=inputs_embeds.device) + attention_mask = attention_mask.to(dtype=hidden_states.dtype) + mask_min_value = torch.finfo(hidden_states.dtype).min + inverted_mask = 1.0 - attention_mask + attention_mask = inverted_mask.masked_fill( + inverted_mask.to(torch.bool), + mask_min_value, + ) + + # padding to block_size + if seq_len % self.config.block_size != 0: + pad_len = self.config.block_size - seq_len % self.config.block_size + hidden_states = nn.functional.pad(hidden_states, pad=(0, 0, 0, pad_len), value=0) + attention_mask = nn.functional.pad(attention_mask, pad=(0, pad_len), value=mask_min_value) + + # Global tokens + global_hidden_states = self.embed_global( + torch.arange(self.config.num_global_tokens, device=hidden_states.device)[None].expand(batch_size, -1) + ) + + encoder_states = () if output_hidden_states else None + all_attentions = () if output_attentions else None + + for idx, encoder_layer in enumerate(self.layers): + if output_hidden_states: + encoder_states = encoder_states + (hidden_states,) + # add LayerDrop (see https://huggingface.co/papers/1909.11556 for description) + to_drop = False + if self.training: + dropout_probability = torch.rand([]) + if dropout_probability < self.layerdrop: # skip the layer + to_drop = True + + if to_drop: + layer_outputs = (None, None) + else: + layer_outputs = encoder_layer( + hidden_states, + global_hidden_states, + attention_mask, + output_attentions=output_attentions, + ) + + hidden_states = layer_outputs[0] + global_hidden_states = layer_outputs[1] + + if output_attentions: + all_attentions = all_attentions + (layer_outputs[2],) + + # Undo padding-to-block-size + hidden_states = hidden_states[:, :seq_len] + + hidden_states = self.layer_norm(hidden_states) + + if output_hidden_states: + encoder_states = encoder_states + ((hidden_states, global_hidden_states),) + + if not return_dict: + return tuple(v for v in [hidden_states, encoder_states, all_attentions] if v is not None) + return BaseModelOutput( + last_hidden_state=hidden_states, hidden_states=encoder_states, attentions=all_attentions + ) + + +class PegasusXDecoder(PegasusXPreTrainedModel): + """ + Transformer decoder consisting of *config.decoder_layers* layers. Each layer is a [`PegasusDecoderLayer`] + + Args: + config: PegasusXConfig + embed_tokens (nn.Embedding): output embedding + """ + + def __init__(self, config: PegasusXConfig): + super().__init__(config) + self.dropout = config.dropout + self.layerdrop = config.decoder_layerdrop + self.max_target_positions = config.max_position_embeddings + embed_scale = math.sqrt(config.d_model) if config.scale_embedding else 1.0 + padding_idx = config.pad_token_id + + self.embed_tokens = PegasusXScaledWordEmbedding( + config.vocab_size, config.d_model, padding_idx=padding_idx, embed_scale=embed_scale + ) + + self.embed_positions = PegasusXSinusoidalPositionalEmbedding(config.d_model) + self.layers = nn.ModuleList([PegasusXDecoderLayer(config, layer_idx=i) for i in range(config.decoder_layers)]) + self.layer_norm = nn.LayerNorm(config.d_model) + + self.gradient_checkpointing = False + # Initialize weights and apply final processing + self.post_init() + + def forward( + self, + input_ids=None, + attention_mask=None, + encoder_hidden_states=None, + encoder_attention_mask=None, + past_key_values=None, + inputs_embeds=None, + use_cache=None, + output_attentions=None, + output_hidden_states=None, + return_dict=None, + cache_position=None, + **kwargs, + ): + r""" + Args: + input_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`): + Indices of input sequence tokens in the vocabulary. Padding will be ignored by default should you + provide it. + + Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and + [`PreTrainedTokenizer.__call__`] for details. + + [What are input IDs?](../glossary#input-ids) + attention_mask (`torch.Tensor` of shape `(batch_size, sequence_length)`, *optional*): + Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`: + + - 1 for tokens that are **not masked**, + - 0 for tokens that are **masked**. + + [What are attention masks?](../glossary#attention-mask) + encoder_hidden_states (`torch.FloatTensor` of shape `(batch_size, encoder_sequence_length, hidden_size)`, *optional*): + Sequence of hidden-states at the output of the last layer of the encoder. Used in the cross-attention + of the decoder. + encoder_attention_mask (`torch.LongTensor` of shape `(batch_size, encoder_sequence_length)`, *optional*): + Mask to avoid performing cross-attention on padding tokens indices of encoder input_ids. Mask values + selected in `[0, 1]`: + + - 1 for tokens that are **not masked**, + - 0 for tokens that are **masked**. + + [What are attention masks?](../glossary#attention-mask) + + past_key_values (`Cache`, *optional*, returned when `use_cache=True` is passed or when `config.use_cache=True`): + It is a [`~cache_utils.Cache`] instance. For more details, see our [kv cache guide](https://huggingface.co/docs/transformers/en/kv_cache). + + Contains pre-computed hidden-states (key and values in the self-attention blocks and in the + cross-attention blocks) that can be used (see `past_key_values` input) to speed up sequential decoding. + + If `past_key_values` are used, the user can optionally input only the last `decoder_input_ids` (those + that don't have their past key value states given to this model) of shape `(batch_size, 1)` instead of + all `decoder_input_ids` of shape `(batch_size, sequence_length)`. + inputs_embeds (`torch.FloatTensor` of + shape `(batch_size, sequence_length, hidden_size)`, *optional*): Optionally, instead of passing + `input_ids` you can choose to directly pass an embedded representation. This is useful if you want more + control over how to convert `input_ids` indices into associated vectors than the model's internal + embedding lookup matrix. + output_attentions (`bool`, *optional*): + Whether or not to return the attentions tensors of all attention layers. See `attentions` under + returned tensors for more detail. + output_hidden_states (`bool`, *optional*): + Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors + for more detail. + return_dict (`bool`, *optional*): + Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple. + cache_position (`torch.LongTensor` of shape `(sequence_length)`, *optional*): + Indices depicting the position of the input sequence tokens in the sequence. It is used to update the + cache in the correct position and to infer the complete sequence length. + """ + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + use_cache = use_cache if use_cache is not None else self.config.use_cache + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + # retrieve input_ids and inputs_embeds + if (input_ids is None) ^ (inputs_embeds is not None): + raise ValueError("You cannot specify both decoder_input_ids and decoder_inputs_embeds at the same time") + elif input_ids is not None: + input = input_ids + input_shape = input.shape + input_ids = input_ids.view(-1, input_shape[-1]) + elif inputs_embeds is not None: + input_shape = inputs_embeds.size()[:-1] + input = inputs_embeds[:, :, -1] + else: + raise ValueError("You have to specify either decoder_input_ids or decoder_inputs_embeds") + + if inputs_embeds is None: + inputs_embeds = self.embed_tokens(input) + + if self.gradient_checkpointing and self.training: + if use_cache: + logger.warning_once( + "`use_cache=True` is incompatible with gradient checkpointing`. Setting `use_cache=False`..." + ) + use_cache = False + + # initialize `past_key_values` + if use_cache and past_key_values is None: + past_key_values = EncoderDecoderCache(DynamicCache(config=self.config), DynamicCache(config=self.config)) + + batch_size, seq_length = inputs_embeds.size()[:-1] + past_key_values_length = past_key_values.get_seq_length() if past_key_values is not None else 0 + if cache_position is None: + cache_position = torch.arange( + past_key_values_length, past_key_values_length + seq_length, device=inputs_embeds.device + ) + + if attention_mask is None and not is_torchdynamo_compiling(): + # required mask seq length can be calculated via length of past cache + mask_seq_length = past_key_values_length + seq_length + attention_mask = torch.ones(batch_size, mask_seq_length, device=inputs_embeds.device) + + self_attn_cache = ( + past_key_values.self_attention_cache + if isinstance(past_key_values, EncoderDecoderCache) + else past_key_values + ) + + causal_mask = create_causal_mask( + config=self.config, + inputs_embeds=inputs_embeds, + attention_mask=attention_mask, + cache_position=cache_position, + past_key_values=self_attn_cache, + ) + encoder_attention_mask = create_bidirectional_mask( + config=self.config, + inputs_embeds=inputs_embeds, + attention_mask=encoder_attention_mask, + encoder_hidden_states=encoder_hidden_states, + ) + + # embed positions + position_ids = cache_position.unsqueeze(1) + position_ids = self.embed_positions(inputs_embeds, past_key_values_length, position_ids) + position_ids = position_ids.to(inputs_embeds.device) + hidden_states = inputs_embeds + position_ids + hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training) + + # decoder layers + all_hidden_states = () if output_hidden_states else None + all_self_attns = () if output_attentions else None + all_cross_attentions = () if (output_attentions and encoder_hidden_states is not None) else None + + for idx, decoder_layer in enumerate(self.layers): + # add LayerDrop (see https://huggingface.co/papers/1909.11556 for description) + if output_hidden_states: + all_hidden_states += (hidden_states,) + if self.training: + dropout_probability = torch.rand([]) + if dropout_probability < self.layerdrop: + continue + + layer_outputs = decoder_layer( + hidden_states, + causal_mask, + encoder_hidden_states, # as a positional argument for gradient checkpointing + encoder_attention_mask=encoder_attention_mask, + past_key_values=past_key_values, + output_attentions=output_attentions, + use_cache=use_cache, + cache_position=cache_position, + ) + hidden_states = layer_outputs[0] + + if output_attentions: + all_self_attns += (layer_outputs[1],) + + if encoder_hidden_states is not None: + all_cross_attentions += (layer_outputs[2],) + + hidden_states = self.layer_norm(hidden_states) + + # add hidden states from the last decoder layer + if output_hidden_states: + all_hidden_states += (hidden_states,) + + if not return_dict: + return tuple( + v + for v in [hidden_states, past_key_values, all_hidden_states, all_self_attns, all_cross_attentions] + if v is not None + ) + return BaseModelOutputWithPastAndCrossAttentions( + last_hidden_state=hidden_states, + past_key_values=past_key_values, + hidden_states=all_hidden_states, + attentions=all_self_attns, + cross_attentions=all_cross_attentions, + ) + + +@auto_docstring +class PegasusXModel(PegasusXPreTrainedModel): + _tied_weights_keys = { + "encoder.embed_tokens.weight": "shared.weight", + "decoder.embed_tokens.weight": "shared.weight", + } + + def __init__(self, config: PegasusXConfig): + super().__init__(config) + + vocab_size = config.vocab_size + embed_scale = math.sqrt(config.d_model) if config.scale_embedding else 1.0 + padding_idx = config.pad_token_id + self.shared = PegasusXScaledWordEmbedding( + vocab_size, config.d_model, padding_idx=padding_idx, embed_scale=embed_scale + ) + + self.encoder = PegasusXEncoder(config) + self.decoder = PegasusXDecoder(config) + + # Initialize weights and apply final processing + self.post_init() + + def get_input_embeddings(self): + return self.shared + + def set_input_embeddings(self, value): + self.shared = value + self.encoder.embed_tokens = self.shared + self.decoder.embed_tokens = self.shared + + def resize_position_embeddings(self, new_num_position_embeddings: int): + """ + Resizes position embeddings matrix of the model if `new_num_position_embeddings != + config.max_position_embeddings`. + + Arguments: + new_num_position_embeddings (`int`): + The number of new position embeddings. If position embeddings are learned, increasing the size will add + newly initialized vectors at the end, whereas reducing the size will remove vectors from the end. If + position embeddings are not learned (*e.g.* sinusoidal position embeddings), increasing the size will + add correct vectors at the end following the position encoding algorithm, whereas reducing the size + will remove vectors from the end. + """ + self.config.max_position_embeddings = new_num_position_embeddings + self.encoder.resize_position_embeddings(new_num_position_embeddings) + self.decoder.resize_position_embeddings(new_num_position_embeddings) + + def get_position_embeddings(self) -> tuple[nn.Embedding]: + """ + Returns the position embeddings matrix + """ + return (self.encoder.get_position_embeddings(), self.decoder.get_position_embeddings()) + + @auto_docstring + def forward( + self, + input_ids: torch.Tensor | None = None, + attention_mask: torch.Tensor | None = None, + decoder_input_ids: torch.Tensor | None = None, + decoder_attention_mask: torch.Tensor | None = None, + encoder_outputs: tuple[torch.FloatTensor] | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.Tensor | None = None, + decoder_inputs_embeds: torch.Tensor | None = None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + cache_position: torch.Tensor | None = None, + **kwargs, + ) -> tuple | Seq2SeqModelOutput: + r""" + decoder_input_ids (`torch.LongTensor` of shape `(batch_size, target_sequence_length)`, *optional*): + Indices of decoder input sequence tokens in the vocabulary. + + Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and + [`PreTrainedTokenizer.__call__`] for details. + + [What are decoder input IDs?](../glossary#decoder-input-ids) + + PEGASUS-X uses the `pad_token_id` as the starting token for `decoder_input_ids` generation. If + `past_key_values` is used, optionally only the last `decoder_input_ids` have to be input (see + `past_key_values`). + decoder_attention_mask (`torch.LongTensor` of shape `(batch_size, target_sequence_length)`, *optional*): + Default behavior: generate a tensor that ignores pad tokens in `decoder_input_ids`. Causal mask will also + be used by default. + + Example: + + ```python + >>> from transformers import AutoTokenizer, PegasusModel + + >>> tokenizer = AutoTokenizer.from_pretrained("google/pegasus-x-large") + >>> model = PegasusModel.from_pretrained("google/pegasus-x-large") + + >>> inputs = tokenizer("Studies have been shown that owning a dog is good for you", return_tensors="pt") + >>> decoder_inputs = tokenizer("Studies show that", return_tensors="pt") + >>> outputs = model(input_ids=inputs.input_ids, decoder_input_ids=decoder_inputs.input_ids) + + >>> last_hidden_states = outputs.last_hidden_state + >>> list(last_hidden_states.shape) + [1, 4, 1024] + ```""" + + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + use_cache = use_cache if use_cache is not None else self.config.use_cache + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + if encoder_outputs is None: + encoder_outputs = self.encoder( + input_ids=input_ids, + attention_mask=attention_mask, + inputs_embeds=inputs_embeds, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + # If the user passed a tuple for encoder_outputs, we wrap it in a BaseModelOutput when return_dict=True + elif return_dict and not isinstance(encoder_outputs, BaseModelOutput): + encoder_outputs = BaseModelOutput( + last_hidden_state=encoder_outputs[0], + hidden_states=encoder_outputs[1] if len(encoder_outputs) > 1 else None, + attentions=encoder_outputs[2] if len(encoder_outputs) > 2 else None, + ) + + # decoder outputs consists of (dec_features, past_key_values, dec_hidden, dec_attn) + decoder_outputs = self.decoder( + input_ids=decoder_input_ids, + attention_mask=decoder_attention_mask, + encoder_hidden_states=encoder_outputs[0], + encoder_attention_mask=attention_mask, + past_key_values=past_key_values, + inputs_embeds=decoder_inputs_embeds, + use_cache=use_cache, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + cache_position=cache_position, + ) + + if not return_dict: + return decoder_outputs + encoder_outputs + + return Seq2SeqModelOutput( + last_hidden_state=decoder_outputs.last_hidden_state, + past_key_values=decoder_outputs.past_key_values, + decoder_hidden_states=decoder_outputs.hidden_states, + decoder_attentions=decoder_outputs.attentions, + cross_attentions=decoder_outputs.cross_attentions, + encoder_last_hidden_state=encoder_outputs.last_hidden_state, + encoder_hidden_states=encoder_outputs.hidden_states, + encoder_attentions=encoder_outputs.attentions, + ) + + +@auto_docstring( + custom_intro=""" + The PEGASUS-X for conditional generation (e.g. summarization). + """ +) +class PegasusXForConditionalGeneration(PegasusXPreTrainedModel, GenerationMixin): + base_model_prefix = "model" + _tied_weights_keys = { + "lm_head.weight": "model.shared.weight", + } + + def __init__(self, config: PegasusXConfig): + super().__init__(config) + self.model = PegasusXModel(config) + self.lm_head = nn.Linear(config.d_model, self.model.shared.num_embeddings, bias=False) + + # Initialize weights and apply final processing + self.post_init() + + def resize_position_embeddings(self, new_num_position_embeddings: int): + """ + Resizes position embeddings matrix of the model if `new_num_position_embeddings != + config.max_position_embeddings`. + + Arguments: + new_num_position_embeddings (`int`): + The number of new position embeddings. If position embeddings are learned, increasing the size will add + newly initialized vectors at the end, whereas reducing the size will remove vectors from the end. If + position embeddings are not learned (*e.g.* sinusoidal position embeddings), increasing the size will + add correct vectors at the end following the position encoding algorithm, whereas reducing the size + will remove vectors from the end. + """ + self.config.max_position_embeddings = new_num_position_embeddings + self.model.encoder.resize_position_embeddings(new_num_position_embeddings) + self.model.decoder.resize_position_embeddings(new_num_position_embeddings) + + def get_position_embeddings(self) -> tuple[nn.Embedding]: + """ + Returns the position embeddings matrix + """ + return (self.model.encoder.get_position_embeddings(), self.model.decoder.get_position_embeddings()) + + @auto_docstring + def forward( + self, + input_ids: torch.Tensor | None = None, + attention_mask: torch.Tensor | None = None, + decoder_input_ids: torch.Tensor | None = None, + decoder_attention_mask: torch.Tensor | None = None, + encoder_outputs: tuple[torch.FloatTensor] | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.Tensor | None = None, + decoder_inputs_embeds: torch.Tensor | None = None, + labels: torch.Tensor | None = None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + cache_position: torch.Tensor | None = None, + **kwargs, + ) -> tuple | Seq2SeqLMOutput: + r""" + decoder_input_ids (`torch.LongTensor` of shape `(batch_size, target_sequence_length)`, *optional*): + Indices of decoder input sequence tokens in the vocabulary. + + Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and + [`PreTrainedTokenizer.__call__`] for details. + + [What are decoder input IDs?](../glossary#decoder-input-ids) + + PEGASUS-X uses the `pad_token_id` as the starting token for `decoder_input_ids` generation. If + `past_key_values` is used, optionally only the last `decoder_input_ids` have to be input (see + `past_key_values`). + decoder_attention_mask (`torch.LongTensor` of shape `(batch_size, target_sequence_length)`, *optional*): + Default behavior: generate a tensor that ignores pad tokens in `decoder_input_ids`. Causal mask will also + be used by default. + labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Labels for computing the masked language modeling loss. Indices should either be in `[0, ..., + config.vocab_size]` or -100 (see `input_ids` docstring). Tokens with indices set to `-100` are ignored + (masked), the loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]`. + """ + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + if labels is not None: + if use_cache: + logger.warning("The `use_cache` argument is changed to `False` since `labels` is provided.") + use_cache = False + if decoder_input_ids is None and decoder_inputs_embeds is None: + decoder_input_ids = shift_tokens_right( + labels, self.config.pad_token_id, self.config.decoder_start_token_id + ) + + outputs = self.model( + input_ids, + attention_mask=attention_mask, + decoder_input_ids=decoder_input_ids, + encoder_outputs=encoder_outputs, + decoder_attention_mask=decoder_attention_mask, + past_key_values=past_key_values, + inputs_embeds=inputs_embeds, + decoder_inputs_embeds=decoder_inputs_embeds, + use_cache=use_cache, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + cache_position=cache_position, + ) + lm_logits = self.lm_head(outputs[0]) + + masked_lm_loss = None + if labels is not None: + loss_fct = CrossEntropyLoss() + masked_lm_loss = loss_fct(lm_logits.view(-1, self.config.vocab_size), labels.view(-1)) + + if not return_dict: + output = (lm_logits,) + outputs[1:] + return ((masked_lm_loss,) + output) if masked_lm_loss is not None else output + + return Seq2SeqLMOutput( + loss=masked_lm_loss, + logits=lm_logits, + past_key_values=outputs.past_key_values, + decoder_hidden_states=outputs.decoder_hidden_states, + decoder_attentions=outputs.decoder_attentions, + cross_attentions=outputs.cross_attentions, + encoder_last_hidden_state=outputs.encoder_last_hidden_state, + encoder_hidden_states=outputs.encoder_hidden_states, + encoder_attentions=outputs.encoder_attentions, + ) + + def prepare_decoder_input_ids_from_labels(self, labels: torch.Tensor): + return shift_tokens_right(labels, self.config.pad_token_id, self.config.decoder_start_token_id) + + +# Copied from transformers.models.bart.modeling_bart.BartDecoderWrapper with Bart->PegasusX +class PegasusXDecoderWrapper(PegasusXPreTrainedModel): + """ + This wrapper class is a helper class to correctly load pretrained checkpoints when the causal language model is + used in combination with the [`EncoderDecoderModel`] framework. + """ + + def __init__(self, config): + super().__init__(config) + self.decoder = PegasusXDecoder(config) + self.post_init() + + def forward(self, *args, **kwargs): + return self.decoder(*args, **kwargs) + + +__all__ = ["PegasusXForConditionalGeneration", "PegasusXModel", "PegasusXPreTrainedModel"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/perceiver/__init__.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/perceiver/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..da8d30a5a9b54b27afb74fba377024c2c95436f6 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/perceiver/__init__.py @@ -0,0 +1,31 @@ +# Copyright 2024 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from typing import TYPE_CHECKING + +from ...utils import _LazyModule +from ...utils.import_utils import define_import_structure + + +if TYPE_CHECKING: + from .configuration_perceiver import * + from .feature_extraction_perceiver import * + from .image_processing_perceiver import * + from .image_processing_perceiver_fast import * + from .modeling_perceiver import * + from .tokenization_perceiver import * +else: + import sys + + _file = globals()["__file__"] + sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__) diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/perceiver/configuration_perceiver.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/perceiver/configuration_perceiver.py new file mode 100644 index 0000000000000000000000000000000000000000..4b2b9635403fd06cc977299226bab1147c62a565 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/perceiver/configuration_perceiver.py @@ -0,0 +1,176 @@ +# Copyright Deepmind and The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""Perceiver model configuration""" + +from ...configuration_utils import PreTrainedConfig +from ...utils import logging + + +logger = logging.get_logger(__name__) + + +class PerceiverConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`PerceiverModel`]. It is used to instantiate an + Perceiver model according to the specified arguments, defining the model architecture. Instantiating a + configuration with the defaults will yield a similar configuration to that of the Perceiver + [deepmind/language-perceiver](https://huggingface.co/deepmind/language-perceiver) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + num_latents (`int`, *optional*, defaults to 256): + The number of latents. + d_latents (`int`, *optional*, defaults to 1280): + Dimension of the latent embeddings. + d_model (`int`, *optional*, defaults to 768): + Dimension of the inputs. Should only be provided in case [*PerceiverTextPreprocessor*] is used or no + preprocessor is provided. + num_blocks (`int`, *optional*, defaults to 1): + Number of blocks in the Transformer encoder. + num_self_attends_per_block (`int`, *optional*, defaults to 26): + The number of self-attention layers per block. + num_self_attention_heads (`int`, *optional*, defaults to 8): + Number of attention heads for each self-attention layer in the Transformer encoder. + num_cross_attention_heads (`int`, *optional*, defaults to 8): + Number of attention heads for each cross-attention layer in the Transformer encoder. + qk_channels (`int`, *optional*): + Dimension to project the queries + keys before applying attention in the cross-attention and self-attention + layers of the encoder. Will default to preserving the dimension of the queries if not specified. + v_channels (`int`, *optional*): + Dimension to project the values before applying attention in the cross-attention and self-attention layers + of the encoder. Will default to preserving the dimension of the queries if not specified. + cross_attention_shape_for_attention (`str`, *optional*, defaults to `"kv"`): + Dimension to use when downsampling the queries and keys in the cross-attention layer of the encoder. + self_attention_widening_factor (`int`, *optional*, defaults to 1): + Dimension of the feed-forward layer in the cross-attention layer of the Transformer encoder. + cross_attention_widening_factor (`int`, *optional*, defaults to 1): + Dimension of the feed-forward layer in the self-attention layers of the Transformer encoder. + hidden_act (`str` or `function`, *optional*, defaults to `"gelu"`): + The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`, + `"relu"`, `"selu"` and `"gelu_new"` are supported. + attention_probs_dropout_prob (`float`, *optional*, defaults to 0.1): + The dropout ratio for the attention probabilities. + initializer_range (`float`, *optional*, defaults to 0.02): + The standard deviation of the truncated_normal_initializer for initializing all weight matrices. + layer_norm_eps (`float`, *optional*, defaults to 1e-12): + The epsilon used by the layer normalization layers. + use_query_residual (`float`, *optional*, defaults to `True`): + Whether to add a query residual in the cross-attention layer of the encoder. + vocab_size (`int`, *optional*, defaults to 262): + Vocabulary size for the masked language modeling model. + max_position_embeddings (`int`, *optional*, defaults to 2048): + The maximum sequence length that the masked language modeling model might ever be used with. Typically set + this to something large just in case (e.g., 512 or 1024 or 2048). + image_size (`int`, *optional*, defaults to 56): + Size of the images after preprocessing, for [`PerceiverForImageClassificationLearned`]. + train_size (`list[int]`, *optional*, defaults to `[368, 496]`): + Training size of the images for the optical flow model. + num_frames (`int`, *optional*, defaults to 16): + Number of video frames used for the multimodal autoencoding model. + audio_samples_per_frame (`int`, *optional*, defaults to 1920): + Number of audio samples per frame for the multimodal autoencoding model. + samples_per_patch (`int`, *optional*, defaults to 16): + Number of audio samples per patch when preprocessing the audio for the multimodal autoencoding model. + output_shape (`list[int]`, *optional*, defaults to `[1, 16, 224, 224]`): + Shape of the output (batch_size, num_frames, height, width) for the video decoder queries of the multimodal + autoencoding model. This excludes the channel dimension. + output_num_channels (`int`, *optional*, defaults to 512): + Number of output channels for each modalitiy decoder. + + Example: + + ```python + >>> from transformers import PerceiverModel, PerceiverConfig + + >>> # Initializing a Perceiver deepmind/language-perceiver style configuration + >>> configuration = PerceiverConfig() + + >>> # Initializing a model from the deepmind/language-perceiver style configuration + >>> model = PerceiverModel(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "perceiver" + + def __init__( + self, + num_latents=256, + d_latents=1280, + d_model=768, + num_blocks=1, + num_self_attends_per_block=26, + num_self_attention_heads=8, + num_cross_attention_heads=8, + qk_channels=None, + v_channels=None, + cross_attention_shape_for_attention="kv", + self_attention_widening_factor=1, + cross_attention_widening_factor=1, + hidden_act="gelu", + attention_probs_dropout_prob=0.1, + initializer_range=0.02, + layer_norm_eps=1e-12, + use_query_residual=True, + vocab_size=262, + max_position_embeddings=2048, + image_size=56, + train_size=[368, 496], + num_frames=16, + audio_samples_per_frame=1920, + samples_per_patch=16, + output_shape=[1, 16, 224, 224], + output_num_channels=512, + _label_trainable_num_channels=1024, + **kwargs, + ): + super().__init__(**kwargs) + + self.num_latents = num_latents + self.d_latents = d_latents + self.d_model = d_model + self.num_blocks = num_blocks + self.num_self_attends_per_block = num_self_attends_per_block + self.num_self_attention_heads = num_self_attention_heads + self.num_cross_attention_heads = num_cross_attention_heads + self.qk_channels = qk_channels + self.v_channels = v_channels + self.cross_attention_shape_for_attention = cross_attention_shape_for_attention + self.self_attention_widening_factor = self_attention_widening_factor + self.cross_attention_widening_factor = cross_attention_widening_factor + self.hidden_act = hidden_act + self.attention_probs_dropout_prob = attention_probs_dropout_prob + self.initializer_range = initializer_range + self.layer_norm_eps = layer_norm_eps + self.use_query_residual = use_query_residual + # masked language modeling attributes + self.vocab_size = vocab_size + self.max_position_embeddings = max_position_embeddings + # image classification attributes + self.image_size = image_size + # flow attributes + self.train_size = train_size + # multimodal autoencoding attributes + self.num_frames = num_frames + self.audio_samples_per_frame = audio_samples_per_frame + self.samples_per_patch = samples_per_patch + self.output_shape = output_shape + self.output_num_channels = output_num_channels + self._label_trainable_num_channels = _label_trainable_num_channels + + +__all__ = ["PerceiverConfig"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/perceiver/image_processing_perceiver.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/perceiver/image_processing_perceiver.py new file mode 100644 index 0000000000000000000000000000000000000000..fdcea93cea9f74800528e4ce0f7df52c56085473 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/perceiver/image_processing_perceiver.py @@ -0,0 +1,345 @@ +# Copyright 2022 The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""Image processor class for Perceiver.""" + +import numpy as np + +from ...image_processing_utils import BaseImageProcessor, BatchFeature, get_size_dict +from ...image_transforms import center_crop, resize, to_channel_dimension_format +from ...image_utils import ( + IMAGENET_DEFAULT_MEAN, + IMAGENET_DEFAULT_STD, + ChannelDimension, + ImageInput, + PILImageResampling, + get_image_size, + infer_channel_dimension_format, + is_scaled_image, + make_flat_list_of_images, + to_numpy_array, + valid_images, + validate_preprocess_arguments, +) +from ...utils import TensorType, filter_out_non_signature_kwargs, is_vision_available, logging +from ...utils.import_utils import requires + + +if is_vision_available(): + import PIL + + +logger = logging.get_logger(__name__) + + +@requires(backends=("vision",)) +class PerceiverImageProcessor(BaseImageProcessor): + r""" + Constructs a Perceiver image processor. + + Args: + do_center_crop (`bool`, `optional`, defaults to `True`): + Whether or not to center crop the image. If the input size if smaller than `crop_size` along any edge, the + image will be padded with zeros and then center cropped. Can be overridden by the `do_center_crop` + parameter in the `preprocess` method. + crop_size (`dict[str, int]`, *optional*, defaults to `{"height": 256, "width": 256}`): + Desired output size when applying center-cropping. Can be overridden by the `crop_size` parameter in the + `preprocess` method. + do_resize (`bool`, *optional*, defaults to `True`): + Whether to resize the image to `(size["height"], size["width"])`. Can be overridden by the `do_resize` + parameter in the `preprocess` method. + size (`dict[str, int]` *optional*, defaults to `{"height": 224, "width": 224}`): + Size of the image after resizing. Can be overridden by the `size` parameter in the `preprocess` method. + resample (`PILImageResampling`, *optional*, defaults to `PILImageResampling.BICUBIC`): + Defines the resampling filter to use if resizing the image. Can be overridden by the `resample` parameter + in the `preprocess` method. + do_rescale (`bool`, *optional*, defaults to `True`): + Whether to rescale the image by the specified scale `rescale_factor`. Can be overridden by the `do_rescale` + parameter in the `preprocess` method. + rescale_factor (`int` or `float`, *optional*, defaults to `1/255`): + Defines the scale factor to use if rescaling the image. Can be overridden by the `rescale_factor` parameter + in the `preprocess` method. + do_normalize: + Whether to normalize the image. Can be overridden by the `do_normalize` parameter in the `preprocess` + method. + image_mean (`float` or `list[float]`, *optional*, defaults to `IMAGENET_STANDARD_MEAN`): + Mean to use if normalizing the image. This is a float or list of floats the length of the number of + channels in the image. Can be overridden by the `image_mean` parameter in the `preprocess` method. + image_std (`float` or `list[float]`, *optional*, defaults to `IMAGENET_STANDARD_STD`): + Standard deviation to use if normalizing the image. This is a float or list of floats the length of the + number of channels in the image. Can be overridden by the `image_std` parameter in the `preprocess` method. + """ + + model_input_names = ["pixel_values"] + + def __init__( + self, + do_center_crop: bool = True, + crop_size: dict[str, int] | None = None, + do_resize: bool = True, + size: dict[str, int] | None = None, + resample: PILImageResampling = PILImageResampling.BICUBIC, + do_rescale: bool = True, + rescale_factor: int | float = 1 / 255, + do_normalize: bool = True, + image_mean: float | list[float] | None = None, + image_std: float | list[float] | None = None, + **kwargs, + ) -> None: + super().__init__(**kwargs) + crop_size = crop_size if crop_size is not None else {"height": 256, "width": 256} + crop_size = get_size_dict(crop_size, param_name="crop_size") + size = size if size is not None else {"height": 224, "width": 224} + size = get_size_dict(size) + + self.do_center_crop = do_center_crop + self.crop_size = crop_size + self.do_resize = do_resize + self.size = size + self.resample = resample + self.do_rescale = do_rescale + self.rescale_factor = rescale_factor + self.do_normalize = do_normalize + self.image_mean = image_mean if image_mean is not None else IMAGENET_DEFAULT_MEAN + self.image_std = image_std if image_std is not None else IMAGENET_DEFAULT_STD + + def center_crop( + self, + image: np.ndarray, + crop_size: dict[str, int], + size: int | None = None, + data_format: str | ChannelDimension | None = None, + input_data_format: str | ChannelDimension | None = None, + **kwargs, + ) -> np.ndarray: + """ + Center crop an image to `(size["height"] / crop_size["height"] * min_dim, size["width"] / crop_size["width"] * + min_dim)`. Where `min_dim = min(size["height"], size["width"])`. + + If the input size is smaller than `crop_size` along any edge, the image will be padded with zeros and then + center cropped. + + Args: + image (`np.ndarray`): + Image to center crop. + crop_size (`dict[str, int]`): + Desired output size after applying the center crop. + size (`dict[str, int]`, *optional*): + Size of the image after resizing. If not provided, the self.size attribute will be used. + data_format (`str` or `ChannelDimension`, *optional*): + The channel dimension format of the image. If not provided, it will be the same as the input image. + input_data_format (`str` or `ChannelDimension`, *optional*): + The channel dimension format of the input image. If not provided, it will be inferred. + """ + size = self.size if size is None else size + size = get_size_dict(size) + crop_size = get_size_dict(crop_size, param_name="crop_size") + + height, width = get_image_size(image, channel_dim=input_data_format) + min_dim = min(height, width) + cropped_height = (size["height"] / crop_size["height"]) * min_dim + cropped_width = (size["width"] / crop_size["width"]) * min_dim + return center_crop( + image, + size=(cropped_height, cropped_width), + data_format=data_format, + input_data_format=input_data_format, + **kwargs, + ) + + # Copied from transformers.models.vit.image_processing_vit.ViTImageProcessor.resize with PILImageResampling.BILINEAR->PILImageResampling.BICUBIC + def resize( + self, + image: np.ndarray, + size: dict[str, int], + resample: PILImageResampling = PILImageResampling.BICUBIC, + data_format: str | ChannelDimension | None = None, + input_data_format: str | ChannelDimension | None = None, + **kwargs, + ) -> np.ndarray: + """ + Resize an image to `(size["height"], size["width"])`. + + Args: + image (`np.ndarray`): + Image to resize. + size (`dict[str, int]`): + Dictionary in the format `{"height": int, "width": int}` specifying the size of the output image. + resample (`PILImageResampling`, *optional*, defaults to `PILImageResampling.BICUBIC`): + `PILImageResampling` filter to use when resizing the image e.g. `PILImageResampling.BICUBIC`. + data_format (`ChannelDimension` or `str`, *optional*): + The channel dimension format for the output image. If unset, the channel dimension format of the input + image is used. Can be one of: + - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format. + - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format. + - `"none"` or `ChannelDimension.NONE`: image in (height, width) format. + input_data_format (`ChannelDimension` or `str`, *optional*): + The channel dimension format for the input image. If unset, the channel dimension format is inferred + from the input image. Can be one of: + - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format. + - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format. + - `"none"` or `ChannelDimension.NONE`: image in (height, width) format. + + Returns: + `np.ndarray`: The resized image. + """ + size = get_size_dict(size) + if "height" not in size or "width" not in size: + raise ValueError(f"The `size` dictionary must contain the keys `height` and `width`. Got {size.keys()}") + output_size = (size["height"], size["width"]) + return resize( + image, + size=output_size, + resample=resample, + data_format=data_format, + input_data_format=input_data_format, + **kwargs, + ) + + @filter_out_non_signature_kwargs() + def preprocess( + self, + images: ImageInput, + do_center_crop: bool | None = None, + crop_size: dict[str, int] | None = None, + do_resize: bool | None = None, + size: dict[str, int] | None = None, + resample: PILImageResampling | None = None, + do_rescale: bool | None = None, + rescale_factor: float | None = None, + do_normalize: bool | None = None, + image_mean: float | list[float] | None = None, + image_std: float | list[float] | None = None, + return_tensors: str | TensorType | None = None, + data_format: ChannelDimension = ChannelDimension.FIRST, + input_data_format: str | ChannelDimension | None = None, + ) -> PIL.Image.Image: + """ + Preprocess an image or batch of images. + + Args: + images (`ImageInput`): + Image to preprocess. Expects a single or batch of images with pixel values ranging from 0 to 255. If + passing in images with pixel values between 0 and 1, set `do_rescale=False`. + do_center_crop (`bool`, *optional*, defaults to `self.do_center_crop`): + Whether to center crop the image to `crop_size`. + crop_size (`dict[str, int]`, *optional*, defaults to `self.crop_size`): + Desired output size after applying the center crop. + do_resize (`bool`, *optional*, defaults to `self.do_resize`): + Whether to resize the image. + size (`dict[str, int]`, *optional*, defaults to `self.size`): + Size of the image after resizing. + resample (`int`, *optional*, defaults to `self.resample`): + Resampling filter to use if resizing the image. This can be one of the enum `PILImageResampling`, Only + has an effect if `do_resize` is set to `True`. + do_rescale (`bool`, *optional*, defaults to `self.do_rescale`): + Whether to rescale the image. + rescale_factor (`float`, *optional*, defaults to `self.rescale_factor`): + Rescale factor to rescale the image by if `do_rescale` is set to `True`. + do_normalize (`bool`, *optional*, defaults to `self.do_normalize`): + Whether to normalize the image. + image_mean (`float` or `list[float]`, *optional*, defaults to `self.image_mean`): + Image mean. + image_std (`float` or `list[float]`, *optional*, defaults to `self.image_std`): + Image standard deviation. + return_tensors (`str` or `TensorType`, *optional*): + The type of tensors to return. Can be one of: + - Unset: Return a list of `np.ndarray`. + - `TensorType.PYTORCH` or `'pt'`: Return a batch of type `torch.Tensor`. + - `TensorType.NUMPY` or `'np'`: Return a batch of type `np.ndarray`. + data_format (`ChannelDimension` or `str`, *optional*, defaults to `ChannelDimension.FIRST`): + The channel dimension format for the output image. Can be one of: + - `ChannelDimension.FIRST`: image in (num_channels, height, width) format. + - `ChannelDimension.LAST`: image in (height, width, num_channels) format. + input_data_format (`ChannelDimension` or `str`, *optional*): + The channel dimension format for the input image. If unset, the channel dimension format is inferred + from the input image. Can be one of: + - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format. + - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format. + - `"none"` or `ChannelDimension.NONE`: image in (height, width) format. + """ + do_center_crop = do_center_crop if do_center_crop is not None else self.do_center_crop + crop_size = crop_size if crop_size is not None else self.crop_size + crop_size = get_size_dict(crop_size, param_name="crop_size") + do_resize = do_resize if do_resize is not None else self.do_resize + size = size if size is not None else self.size + size = get_size_dict(size) + resample = resample if resample is not None else self.resample + do_rescale = do_rescale if do_rescale is not None else self.do_rescale + rescale_factor = rescale_factor if rescale_factor is not None else self.rescale_factor + do_normalize = do_normalize if do_normalize is not None else self.do_normalize + image_mean = image_mean if image_mean is not None else self.image_mean + image_std = image_std if image_std is not None else self.image_std + + images = make_flat_list_of_images(images) + + if not valid_images(images): + raise ValueError("Invalid image type. Must be of type PIL.Image.Image, numpy.ndarray, or torch.Tensor") + validate_preprocess_arguments( + do_rescale=do_rescale, + rescale_factor=rescale_factor, + do_normalize=do_normalize, + image_mean=image_mean, + image_std=image_std, + do_center_crop=do_center_crop, + crop_size=crop_size, + do_resize=do_resize, + size=size, + resample=resample, + ) + + # All transformations expect numpy arrays. + images = [to_numpy_array(image) for image in images] + + if do_rescale and is_scaled_image(images[0]): + logger.warning_once( + "It looks like you are trying to rescale already rescaled images. If the input" + " images have pixel values between 0 and 1, set `do_rescale=False` to avoid rescaling them again." + ) + + if input_data_format is None: + # We assume that all images have the same channel dimension format. + input_data_format = infer_channel_dimension_format(images[0]) + + if do_center_crop: + images = [ + self.center_crop(image, crop_size, size=size, input_data_format=input_data_format) for image in images + ] + + if do_resize: + images = [ + self.resize(image=image, size=size, resample=resample, input_data_format=input_data_format) + for image in images + ] + + if do_rescale: + images = [ + self.rescale(image=image, scale=rescale_factor, input_data_format=input_data_format) + for image in images + ] + + if do_normalize: + images = [ + self.normalize(image=image, mean=image_mean, std=image_std, input_data_format=input_data_format) + for image in images + ] + + images = [ + to_channel_dimension_format(image, data_format, input_channel_dim=input_data_format) for image in images + ] + + data = {"pixel_values": images} + return BatchFeature(data=data, tensor_type=return_tensors) + + +__all__ = ["PerceiverImageProcessor"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/perceiver/image_processing_perceiver_fast.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/perceiver/image_processing_perceiver_fast.py new file mode 100644 index 0000000000000000000000000000000000000000..aec26d3e37930376ee28e36d36f0e44142f397e5 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/perceiver/image_processing_perceiver_fast.py @@ -0,0 +1,119 @@ +# Copyright 2025 The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""Fast Image processor class for Perceiver.""" + +from typing import Optional + +import torch +import torchvision.transforms.v2.functional as tvF + +from ...image_processing_utils_fast import BaseImageProcessorFast, BatchFeature +from ...image_transforms import group_images_by_shape, reorder_images +from ...image_utils import IMAGENET_DEFAULT_MEAN, IMAGENET_DEFAULT_STD, PILImageResampling, SizeDict +from ...utils import ( + TensorType, + auto_docstring, +) + + +@auto_docstring +class PerceiverImageProcessorFast(BaseImageProcessorFast): + resample = PILImageResampling.BICUBIC + image_mean = IMAGENET_DEFAULT_MEAN + image_std = IMAGENET_DEFAULT_STD + size = {"height": 224, "width": 224} + crop_size = {"height": 256, "width": 256} + do_resize = True + do_center_crop = True + do_rescale = True + do_normalize = True + + def center_crop( + self, + image: "torch.Tensor", + crop_size: dict[str, int], + size: dict[str, int], + **kwargs, + ) -> "torch.Tensor": + """ + Center crop an image to `(size["height"] / crop_size["height"] * min_dim, size["width"] / crop_size["width"] * + min_dim)`. Where `min_dim = min(size["height"], size["width"])`. + + If the input size is smaller than `crop_size` along any edge, the image will be padded with zeros and then + center cropped. + + Args: + image (`"torch.Tensor"`): + Image to center crop. + crop_size (`dict[str, int]`): + Desired output size after applying the center crop. + size (`dict[str, int]`): + Size of the output image. + + Returns: + `torch.Tensor`: The center cropped image. + """ + if size.height is None or size.width is None: + raise ValueError(f"The size dictionary must have keys 'height' and 'width'. Got {size.keys()}") + height, width = image.shape[-2:] + min_dim = min(height, width) + cropped_height = int((size.height / crop_size.height) * min_dim) + cropped_width = int((size.width / crop_size.width) * min_dim) + return super().center_crop(image, SizeDict(height=cropped_height, width=cropped_width)) + + def _preprocess( + self, + images: list["torch.Tensor"], + do_resize: bool, + size: SizeDict, + interpolation: Optional["tvF.InterpolationMode"], + do_center_crop: bool, + crop_size: SizeDict, + do_rescale: bool, + rescale_factor: float, + do_normalize: bool, + image_mean: float | list[float] | None, + image_std: float | list[float] | None, + disable_grouping: bool | None, + return_tensors: str | TensorType | None, + **kwargs, + ) -> BatchFeature: + # Group images by size for batched resizing + grouped_images, grouped_images_index = group_images_by_shape(images, disable_grouping=disable_grouping) + resized_images_grouped = {} + for shape, stacked_images in grouped_images.items(): + if do_center_crop: + stacked_images = self.center_crop(stacked_images, size=size, crop_size=crop_size) + if do_resize: + stacked_images = self.resize(image=stacked_images, size=size, interpolation=interpolation) + resized_images_grouped[shape] = stacked_images + resized_images = reorder_images(resized_images_grouped, grouped_images_index) + + # Group images by size for further processing + # Needed in case do_resize is False, or resize returns images with different sizes + grouped_images, grouped_images_index = group_images_by_shape(resized_images, disable_grouping=disable_grouping) + processed_images_grouped = {} + for shape, stacked_images in grouped_images.items(): + # Fused rescale and normalize + stacked_images = self.rescale_and_normalize( + stacked_images, do_rescale, rescale_factor, do_normalize, image_mean, image_std + ) + processed_images_grouped[shape] = stacked_images + + processed_images = reorder_images(processed_images_grouped, grouped_images_index) + + return BatchFeature(data={"pixel_values": processed_images}, tensor_type=return_tensors) + + +__all__ = ["PerceiverImageProcessorFast"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/perceiver/modeling_perceiver.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/perceiver/modeling_perceiver.py new file mode 100644 index 0000000000000000000000000000000000000000..02f67aca7908f9da7917faed56a06b568d0f88f6 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/perceiver/modeling_perceiver.py @@ -0,0 +1,3302 @@ +# Copyright 2021 Deepmind and The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""PyTorch Perceiver model.""" + +import abc +import math +from collections.abc import Callable, Mapping +from dataclasses import dataclass +from functools import reduce +from operator import __add__ +from typing import Any, Optional + +import numpy as np +import torch +from torch import nn +from torch.nn import BCEWithLogitsLoss, CrossEntropyLoss, MSELoss + +from ... import initialization as init +from ...activations import ACT2FN +from ...modeling_outputs import BaseModelOutputWithCrossAttentions +from ...modeling_utils import PreTrainedModel +from ...pytorch_utils import apply_chunking_to_forward +from ...utils import ModelOutput, auto_docstring, logging, torch_int +from .configuration_perceiver import PerceiverConfig + + +ModalitySizeType = Mapping[str, int] +PreprocessorOutputType = tuple[torch.Tensor, torch.Tensor | None, torch.Tensor] +PreprocessorType = Callable[..., PreprocessorOutputType] +PostprocessorType = Callable[..., Any] + +logger = logging.get_logger(__name__) + + +@dataclass +@auto_docstring( + custom_intro=""" + Base class for Perceiver base model's outputs, with potential hidden states, attentions and cross-attentions. + """ +) +class PerceiverModelOutput(ModelOutput): + r""" + logits (`torch.FloatTensor` of shape `(batch_size, num_labels)`): + Classification (or regression if config.num_labels==1) scores (before SoftMax). + """ + + logits: torch.FloatTensor | None = None + last_hidden_state: torch.FloatTensor | None = None + hidden_states: tuple[torch.FloatTensor] | None = None + attentions: tuple[torch.FloatTensor] | None = None + cross_attentions: tuple[torch.FloatTensor] | None = None + + +@dataclass +@auto_docstring( + custom_intro=""" + Base class for Perceiver decoder outputs, with potential cross-attentions. + """ +) +class PerceiverDecoderOutput(ModelOutput): + r""" + logits (`torch.FloatTensor` of shape `(batch_size, num_labels)`): + Output of the basic decoder. + """ + + logits: torch.FloatTensor | None = None + cross_attentions: tuple[torch.FloatTensor] | None = None + + +@dataclass +@auto_docstring( + custom_intro=""" + Base class for Perceiver's masked language model outputs. + """ +) +class PerceiverMaskedLMOutput(ModelOutput): + r""" + loss (`torch.FloatTensor` of shape `(1,)`, *optional*, returned when `labels` is provided): + Masked language modeling (MLM) loss. + logits (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.vocab_size)`): + Prediction scores of the language modeling head (scores for each vocabulary token before SoftMax). + """ + + loss: torch.FloatTensor | None = None + logits: torch.FloatTensor | None = None + hidden_states: tuple[torch.FloatTensor] | None = None + attentions: tuple[torch.FloatTensor] | None = None + cross_attentions: tuple[torch.FloatTensor] | None = None + + +@dataclass +@auto_docstring( + custom_intro=""" + Base class for Perceiver's outputs of sequence/image classification models, optical flow and multimodal + autoencoding. + """ +) +class PerceiverClassifierOutput(ModelOutput): + r""" + loss (`torch.FloatTensor` of shape `(1,)`, *optional*, returned when `labels` is provided): + Classification (or regression if config.num_labels==1) loss. + logits (`torch.FloatTensor` of shape `(batch_size, config.num_labels)`): + Classification (or regression if config.num_labels==1) scores (before SoftMax). + """ + + loss: torch.FloatTensor | None = None + logits: torch.FloatTensor | None = None + hidden_states: tuple[torch.FloatTensor] | None = None + attentions: tuple[torch.FloatTensor] | None = None + cross_attentions: tuple[torch.FloatTensor] | None = None + + +class PerceiverEmbeddings(nn.Module): + """Construct the latent embeddings.""" + + def __init__(self, config): + super().__init__() + self.latents = nn.Parameter(torch.randn(config.num_latents, config.d_latents)) + + def forward(self, batch_size: int): + return self.latents.expand(batch_size, -1, -1) # Thanks, Phil Wang + + +class PerceiverSelfAttention(nn.Module): + """Multi-headed {cross, self}-attention. Can be used both in the encoder as well as in the decoder.""" + + def __init__( + self, + config, + is_cross_attention=False, + qk_channels=None, + v_channels=None, + num_heads=1, + q_dim=None, + kv_dim=None, + ): + super().__init__() + self.num_heads = num_heads + # Q and K must have the same number of channels. + # Default to preserving Q's input's shape. + if qk_channels is None: + qk_channels = q_dim + # V's num_channels determines the shape of the output of QKV-attention. + # Default to the same number of channels used in the key-query operation. + if v_channels is None: + v_channels = qk_channels + if qk_channels % num_heads != 0: + raise ValueError(f"qk_channels ({qk_channels}) must be divisible by num_heads ({num_heads}).") + if v_channels % num_heads != 0: + raise ValueError(f"v_channels ({v_channels}) must be divisible by num_heads ({num_heads}).") + + self.qk_channels = qk_channels + self.v_channels = v_channels + self.qk_channels_per_head = self.qk_channels // num_heads + self.v_channels_per_head = self.v_channels // num_heads + + # Layer normalization + self.layernorm1 = nn.LayerNorm(q_dim) + self.layernorm2 = nn.LayerNorm(kv_dim) if is_cross_attention else nn.Identity() + + # Projection matrices + self.query = nn.Linear(q_dim, qk_channels) + self.key = nn.Linear(kv_dim, qk_channels) + self.value = nn.Linear(kv_dim, v_channels) + + self.dropout = nn.Dropout(config.attention_probs_dropout_prob) + + def transpose_for_scores(self, x, channels_per_head): + new_x_shape = x.size()[:-1] + (self.num_heads, channels_per_head) + x = x.view(*new_x_shape) + return x.permute(0, 2, 1, 3) + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.FloatTensor | None = None, + inputs: torch.FloatTensor | None = None, + inputs_mask: torch.FloatTensor | None = None, + output_attentions: bool | None = False, + ) -> tuple[torch.Tensor]: + hidden_states = self.layernorm1(hidden_states) + inputs = self.layernorm2(inputs) + + # Project queries, keys and values to a common feature dimension. If this is instantiated as a cross-attention module, + # the keys and values come from the inputs; the attention mask needs to be such that the inputs's non-relevant tokens are not attended to. + is_cross_attention = inputs is not None + queries = self.query(hidden_states) + + if is_cross_attention: + keys = self.key(inputs) + values = self.value(inputs) + attention_mask = inputs_mask + else: + keys = self.key(hidden_states) + values = self.value(hidden_states) + + # Reshape channels for multi-head attention. + # We reshape from (batch_size, time, channels) to (batch_size, num_heads, time, channels per head) + queries = self.transpose_for_scores(queries, self.qk_channels_per_head) + keys = self.transpose_for_scores(keys, self.qk_channels_per_head) + values = self.transpose_for_scores(values, self.v_channels_per_head) + + # Take the dot product between the queries and keys to get the raw attention scores. + attention_scores = torch.matmul(queries, keys.transpose(-1, -2)) + + batch_size, num_heads, seq_len, q_head_dim = queries.shape + _, _, _, v_head_dim = values.shape + hiddens = self.num_heads * v_head_dim + + attention_scores = attention_scores / math.sqrt(q_head_dim) + + if attention_mask is not None: + # Apply the attention mask (precomputed for all layers in PerceiverModel forward() function) + attention_scores = attention_scores + attention_mask + + # Normalize the attention scores to probabilities. + attention_probs = nn.Softmax(dim=-1)(attention_scores) + + # This is actually dropping out entire tokens to attend to, which might + # seem a bit unusual, but is taken from the original Transformer paper. + attention_probs = self.dropout(attention_probs) + + context_layer = torch.matmul(attention_probs, values) + + context_layer = context_layer.permute(0, 2, 1, 3).contiguous() + new_context_layer_shape = context_layer.size()[:-2] + (hiddens,) + context_layer = context_layer.view(*new_context_layer_shape) + + outputs = (context_layer, attention_probs) if output_attentions else (context_layer,) + + return outputs + + +class PerceiverSelfOutput(nn.Module): + def __init__(self, config, input_channels, output_channels): + super().__init__() + self.dense = nn.Linear(input_channels, output_channels) + + def forward(self, hidden_states: torch.Tensor) -> torch.Tensor: + hidden_states = self.dense(hidden_states) + return hidden_states + + +class PerceiverAttention(nn.Module): + """Attention module, including a dense block.""" + + def __init__( + self, + config, + is_cross_attention=False, + qk_channels=None, + v_channels=None, + num_heads=1, + q_dim=None, + kv_dim=None, + use_query_residual=True, + ): + super().__init__() + # MultiHead attention + if is_cross_attention and qk_channels is None: + if config.cross_attention_shape_for_attention == "q": + qk_channels = q_dim + elif config.cross_attention_shape_for_attention == "kv": + qk_channels = kv_dim + else: + raise ValueError( + f"Unknown value {config.cross_attention_shape_for_attention} for " + "cross_attention_shape_for_attention." + ) + else: + if qk_channels is None: + qk_channels = q_dim + if v_channels is None: + v_channels = qk_channels + self.self = PerceiverSelfAttention( + config, + is_cross_attention=is_cross_attention, + qk_channels=qk_channels, + v_channels=v_channels, + num_heads=num_heads, + q_dim=q_dim, + kv_dim=kv_dim, + ) + # dense block + output_channels = None + if is_cross_attention: + output_channels = q_dim + else: + if output_channels is None: + output_channels = v_channels + self.output = PerceiverSelfOutput(config, input_channels=self.self.v_channels, output_channels=output_channels) + self.use_query_residual = use_query_residual + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.FloatTensor | None = None, + inputs: torch.FloatTensor | None = None, + inputs_mask: torch.FloatTensor | None = None, + output_attentions: bool | None = False, + ) -> tuple[torch.Tensor]: + self_outputs = self.self( + hidden_states, + attention_mask, + inputs, + inputs_mask, + output_attentions, + ) + + # Output projection + attention_output = self.output(self_outputs[0]) + + # Optionally include a residual to the original queries. + # Consider omitting the residual if the semantics of query and output + # are different, e.g. if queries are positions and outputs are pixels. + if self.use_query_residual: + attention_output = attention_output + hidden_states + + outputs = (attention_output,) + self_outputs[1:] # add attentions if we output them + return outputs + + +class PerceiverMLP(nn.Module): + """A Transformer-style dense module to follow attention.""" + + def __init__(self, config, input_size, widening_factor): + super().__init__() + self.dense1 = nn.Linear(input_size, widening_factor * input_size) + if isinstance(config.hidden_act, str): + self.intermediate_act_fn = ACT2FN[config.hidden_act] + else: + self.intermediate_act_fn = config.hidden_act + self.dense2 = nn.Linear(widening_factor * input_size, input_size) + + def forward(self, hidden_states: torch.Tensor) -> torch.Tensor: + hidden_states = self.dense1(hidden_states) + hidden_states = self.intermediate_act_fn(hidden_states) + hidden_states = self.dense2(hidden_states) + return hidden_states + + +class PerceiverLayer(nn.Module): + def __init__( + self, + config, + is_cross_attention=False, + qk_channels=None, + v_channels=None, + num_heads=1, + q_dim=None, + kv_dim=None, + widening_factor=4, + use_query_residual=True, + ): + super().__init__() + self.chunk_size_feed_forward = config.chunk_size_feed_forward + self.seq_len_dim = 1 + self.attention = PerceiverAttention( + config, + is_cross_attention=is_cross_attention, + qk_channels=qk_channels, + v_channels=v_channels, + num_heads=num_heads, + q_dim=q_dim, + kv_dim=kv_dim, + use_query_residual=use_query_residual, + ) + self.layernorm = nn.LayerNorm(q_dim) + self.mlp = PerceiverMLP(config, input_size=q_dim, widening_factor=widening_factor) + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.FloatTensor | None = None, + inputs: torch.FloatTensor | None = None, + inputs_mask: torch.FloatTensor | None = None, + output_attentions: bool | None = False, + ) -> tuple[torch.Tensor]: + attention_outputs = self.attention( + hidden_states, + attention_mask, + inputs, + inputs_mask, + output_attentions, + ) + attention_output = attention_outputs[0] + + outputs = attention_outputs[1:] # add attentions if we output attention weights + + layer_output = apply_chunking_to_forward( + self.feed_forward_chunk, self.chunk_size_feed_forward, self.seq_len_dim, attention_output + ) + + layer_output = layer_output + attention_output # residual connection + + outputs = (layer_output,) + outputs + + return outputs + + def feed_forward_chunk(self, attention_output): + layer_output = self.layernorm(attention_output) + layer_output = self.mlp(layer_output) + return layer_output + + +class PerceiverEncoder(nn.Module): + """The Perceiver Encoder: a scalable, fully attentional encoder.""" + + def __init__(self, config, kv_dim=None): + super().__init__() + self.config = config + + # Check that we can use multihead-attention with these shapes. + if config.d_latents % config.num_self_attention_heads != 0: + raise ValueError( + f"num_z_channels ({config.d_latents}) must be divisible by" + f" num_self_attend_heads ({config.num_self_attention_heads})." + ) + if config.d_latents % config.num_cross_attention_heads != 0: + raise ValueError( + f"num_z_channels ({config.d_latents}) must be divisible by" + f" num_cross_attend_heads ({config.num_cross_attention_heads})." + ) + + # Construct the cross attention layer. + self.cross_attention = PerceiverLayer( + config, + is_cross_attention=True, + qk_channels=config.qk_channels, + v_channels=config.v_channels, + num_heads=config.num_cross_attention_heads, + q_dim=config.d_latents, + kv_dim=kv_dim, + widening_factor=config.cross_attention_widening_factor, + use_query_residual=config.use_query_residual, + ) + + # Construct a single block of self-attention layers. + # We get deeper architectures by applying this block more than once. + self_attention_layers = [] + for _ in range(config.num_self_attends_per_block): + layer = PerceiverLayer( + config, + is_cross_attention=False, + qk_channels=config.qk_channels, + v_channels=config.v_channels, + num_heads=config.num_self_attention_heads, + q_dim=config.d_latents, + kv_dim=config.d_latents, + widening_factor=config.self_attention_widening_factor, + ) + self_attention_layers.append(layer) + + self.self_attends = nn.ModuleList(self_attention_layers) + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.FloatTensor | None = None, + inputs: torch.FloatTensor | None = None, + inputs_mask: torch.FloatTensor | None = None, + output_attentions: bool | None = False, + output_hidden_states: bool | None = False, + return_dict: bool | None = True, + ) -> tuple | BaseModelOutputWithCrossAttentions: + all_hidden_states = () if output_hidden_states else None + all_self_attentions = () if output_attentions else None + all_cross_attentions = () if output_attentions else None + + # Apply the cross-attention between the latents (hidden_states) and inputs: + layer_outputs = self.cross_attention( + hidden_states, + attention_mask=attention_mask, + inputs=inputs, + inputs_mask=inputs_mask, + output_attentions=output_attentions, + ) + hidden_states = layer_outputs[0] + + if output_attentions: + all_cross_attentions = all_cross_attentions + (layer_outputs[1],) + + # Apply the block of self-attention layers more than once: + for _ in range(self.config.num_blocks): + for i, layer_module in enumerate(self.self_attends): + if output_hidden_states: + all_hidden_states = all_hidden_states + (hidden_states,) + + layer_outputs = layer_module( + hidden_states, + attention_mask=attention_mask, + output_attentions=output_attentions, + ) + + hidden_states = layer_outputs[0] + if output_attentions: + all_self_attentions = all_self_attentions + (layer_outputs[1],) + + if output_hidden_states: + all_hidden_states = all_hidden_states + (hidden_states,) + + if not return_dict: + return tuple( + v + for v in [hidden_states, all_hidden_states, all_self_attentions, all_cross_attentions] + if v is not None + ) + return BaseModelOutputWithCrossAttentions( + last_hidden_state=hidden_states, + hidden_states=all_hidden_states, + attentions=all_self_attentions, + cross_attentions=all_cross_attentions, + ) + + +@auto_docstring +class PerceiverPreTrainedModel(PreTrainedModel): + config: PerceiverConfig + base_model_prefix = "perceiver" + main_input_name = "inputs" + input_modalities = ("image",) # techinically can be anything but HF impl has only image processor + + @torch.no_grad() + def _init_weights(self, module): + """Initialize the weights""" + if isinstance(module, (nn.Linear, nn.Conv2d)): + init.normal_(module.weight, mean=0.0, std=self.config.initializer_range) + if module.bias is not None: + init.zeros_(module.bias) + elif hasattr(module, "latents"): + init.normal_(module.latents, mean=0.0, std=self.config.initializer_range) + elif hasattr(module, "position_embeddings") and isinstance(module, PerceiverTrainablePositionEncoding): + init.normal_(module.position_embeddings, mean=0.0, std=self.config.initializer_range) + elif isinstance(module, nn.ParameterDict): + for modality in module: + init.normal_(module[modality], mean=0.0, std=self.config.initializer_range) + elif isinstance(module, nn.Embedding): + init.normal_(module.weight, mean=0.0, std=self.config.initializer_range) + # Here we need the check explicitly, as we slice the weight in the `zeros_` call, so it looses the flag + if module.padding_idx is not None and not getattr(module.weight, "_is_hf_initialized", False): + init.zeros_(module.weight[module.padding_idx]) + elif isinstance(module, (nn.LayerNorm, nn.BatchNorm2d)): + init.zeros_(module.bias) + init.ones_(module.weight) + if getattr(module, "running_mean", None) is not None: + init.zeros_(module.running_mean) + init.ones_(module.running_var) + init.zeros_(module.num_batches_tracked) + + +@auto_docstring( + custom_intro=""" + The Perceiver: a scalable, fully attentional architecture. + + + + Note that it's possible to fine-tune Perceiver on higher resolution images than the ones it has been trained on, by + setting `interpolate_pos_encoding` to `True` in the forward of the model. This will interpolate the pre-trained + position embeddings to the higher resolution. + + + """ +) +class PerceiverModel(PerceiverPreTrainedModel): + def __init__( + self, + config, + decoder: Optional["PerceiverAbstractDecoder"] = None, + input_preprocessor: PreprocessorType = None, + output_postprocessor: PostprocessorType = None, + ): + r""" + decoder (`PerceiverDecoder`, *optional*): + Decoder module that transforms latent representations into task predictions. + input_preprocessor (`PreprocessorType`, *optional*): + Preprocessor that encodes raw inputs into tensors for the model. + output_postprocessor (`PostprocessorType`, *optional*): + Postprocessor that transforms model outputs into final predictions. + """ + super().__init__(config) + self.config = config + + self.input_preprocessor = input_preprocessor + self.output_postprocessor = output_postprocessor + self.embeddings = PerceiverEmbeddings(config) + self.encoder = PerceiverEncoder( + config, kv_dim=input_preprocessor.num_channels if input_preprocessor is not None else config.d_model + ) + self.decoder = decoder + + # Initialize weights and apply final processing + self.post_init() + + def get_input_embeddings(self): + return self.embeddings.latents + + def set_input_embeddings(self, value): + self.embeddings.latents = value + + @auto_docstring + def forward( + self, + inputs: torch.FloatTensor, + attention_mask: torch.FloatTensor | None = None, + subsampled_output_points: dict[str, torch.Tensor] | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + interpolate_pos_encoding: bool = False, + return_dict: bool | None = None, + **kwargs, + ) -> tuple | PerceiverModelOutput: + r""" + inputs (`torch.FloatTensor`): + Inputs to the perceiver. Can be anything: images, text, audio, video, etc. + subsampled_output_points (`dict[str, torch.Tensor]`, *optional*): + Dictionary of tensors used as queries for the decoder. The decoder maps these queries to the latent + representation of the model. Used for subsampled decoding, e.g. when only decoding certain image patches. + + Examples: + + ```python + >>> from transformers import PerceiverConfig, PerceiverTokenizer, PerceiverImageProcessor, PerceiverModel + >>> from transformers.models.perceiver.modeling_perceiver import ( + ... PerceiverTextPreprocessor, + ... PerceiverImagePreprocessor, + ... PerceiverClassificationDecoder, + ... ) + >>> import torch + >>> import httpx + >>> from io import BytesIO + >>> from PIL import Image + + >>> # EXAMPLE 1: using the Perceiver to classify texts + >>> # - we define a TextPreprocessor, which can be used to embed tokens + >>> # - we define a ClassificationDecoder, which can be used to decode the + >>> # final hidden states of the latents to classification logits + >>> # using trainable position embeddings + >>> config = PerceiverConfig() + >>> preprocessor = PerceiverTextPreprocessor(config) + >>> decoder = PerceiverClassificationDecoder( + ... config, + ... num_channels=config.d_latents, + ... trainable_position_encoding_kwargs=dict(num_channels=config.d_latents, index_dims=1), + ... use_query_residual=True, + ... ) + >>> model = PerceiverModel(config, input_preprocessor=preprocessor, decoder=decoder) + + >>> # you can then do a forward pass as follows: + >>> tokenizer = PerceiverTokenizer() + >>> text = "hello world" + >>> inputs = tokenizer(text, return_tensors="pt").input_ids + + >>> with torch.no_grad(): + ... outputs = model(inputs=inputs) + >>> logits = outputs.logits + >>> list(logits.shape) + [1, 2] + + >>> # to train, one can train the model using standard cross-entropy: + >>> criterion = torch.nn.CrossEntropyLoss() + + >>> labels = torch.tensor([1]) + >>> loss = criterion(logits, labels) + + >>> # EXAMPLE 2: using the Perceiver to classify images + >>> # - we define an ImagePreprocessor, which can be used to embed images + >>> config = PerceiverConfig(image_size=224) + >>> preprocessor = PerceiverImagePreprocessor( + ... config, + ... prep_type="conv1x1", + ... spatial_downsample=1, + ... out_channels=256, + ... position_encoding_type="trainable", + ... concat_or_add_pos="concat", + ... project_pos_dim=256, + ... trainable_position_encoding_kwargs=dict( + ... num_channels=256, + ... index_dims=config.image_size**2, + ... ), + ... ) + + >>> model = PerceiverModel( + ... config, + ... input_preprocessor=preprocessor, + ... decoder=PerceiverClassificationDecoder( + ... config, + ... num_channels=config.d_latents, + ... trainable_position_encoding_kwargs=dict(num_channels=config.d_latents, index_dims=1), + ... use_query_residual=True, + ... ), + ... ) + + >>> # you can then do a forward pass as follows: + >>> image_processor = PerceiverImageProcessor() + >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg" + >>> with httpx.stream("GET", url) as response: + ... image = Image.open(BytesIO(response.read())) + >>> inputs = image_processor(image, return_tensors="pt").pixel_values + + >>> with torch.no_grad(): + ... outputs = model(inputs=inputs) + >>> logits = outputs.logits + >>> list(logits.shape) + [1, 2] + + >>> # to train, one can train the model using standard cross-entropy: + >>> criterion = torch.nn.CrossEntropyLoss() + + >>> labels = torch.tensor([1]) + >>> loss = criterion(logits, labels) + ```""" + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + if self.input_preprocessor is not None: + inputs, modality_sizes, inputs_without_pos = self.input_preprocessor( + inputs, interpolate_pos_encoding=interpolate_pos_encoding + ) + else: + modality_sizes = None + inputs_without_pos = None + if inputs.size()[-1] != self.config.d_model: + raise ValueError( + f"Last dimension of the inputs: {inputs.size()[-1]} doesn't correspond to config.d_model:" + f" {self.config.d_model}. Make sure to set config.d_model appropriately." + ) + + batch_size, seq_length, _ = inputs.size() + device = inputs.device + + # If no attention mask is provided, make them all ones + if attention_mask is None: + attention_mask = torch.ones((batch_size, seq_length), device=device) + # Make the attention mask broadcastable to [batch_size, num_heads, seq_length, seq_length] + extended_attention_mask = self.invert_attention_mask(attention_mask) + + embedding_output = self.embeddings(batch_size=batch_size) + + encoder_outputs = self.encoder( + embedding_output, + attention_mask=None, + inputs=inputs, + inputs_mask=extended_attention_mask, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + sequence_output = encoder_outputs[0] + + logits = None + if self.decoder: + if subsampled_output_points is not None: + output_modality_sizes = { + "audio": subsampled_output_points["audio"].shape[0], + "image": subsampled_output_points["image"].shape[0], + "label": 1, + } + else: + output_modality_sizes = modality_sizes + decoder_query = self.decoder.decoder_query( + inputs, modality_sizes, inputs_without_pos, subsampled_points=subsampled_output_points + ) + decoder_outputs = self.decoder( + decoder_query, + z=sequence_output, + query_mask=extended_attention_mask, + output_attentions=output_attentions, + ) + logits = decoder_outputs.logits + + # add cross-attentions of decoder + if output_attentions and decoder_outputs.cross_attentions is not None: + if return_dict: + encoder_outputs.cross_attentions = ( + encoder_outputs.cross_attentions + decoder_outputs.cross_attentions + ) + else: + encoder_outputs = encoder_outputs + decoder_outputs.cross_attentions + + if self.output_postprocessor: + logits = self.output_postprocessor(logits, modality_sizes=output_modality_sizes) + + if not return_dict: + if logits is not None: + return (logits, sequence_output) + encoder_outputs[1:] + else: + return (sequence_output,) + encoder_outputs[1:] + + return PerceiverModelOutput( + logits=logits, + last_hidden_state=sequence_output, + hidden_states=encoder_outputs.hidden_states, + attentions=encoder_outputs.attentions, + cross_attentions=encoder_outputs.cross_attentions, + ) + + +@auto_docstring( + custom_intro=""" + Example use of Perceiver for masked language modeling. + """ +) +class PerceiverForMaskedLM(PerceiverPreTrainedModel): + def __init__(self, config: PerceiverConfig): + super().__init__(config) + + text_preprocessor = PerceiverTextPreprocessor(config) + + trainable_position_encoding_kwargs_decoder = { + "num_channels": text_preprocessor.num_channels, + "index_dims": config.max_position_embeddings, + } + + self.perceiver = PerceiverModel( + config, + input_preprocessor=text_preprocessor, + decoder=PerceiverBasicDecoder( + config, + output_num_channels=config.d_latents, + output_index_dims=config.max_position_embeddings, # we need to define the seq_len of the inputs beforehand + num_channels=text_preprocessor.num_channels, + qk_channels=8 * 32, + v_channels=text_preprocessor.num_channels, + num_heads=8, + use_query_residual=False, + final_project=False, + trainable_position_encoding_kwargs=trainable_position_encoding_kwargs_decoder, + ), + ) + self.embedding_decoder = PerceiverEmbeddingDecoder(config) + + # Initialize weights and apply final processing + self.post_init() + + @auto_docstring + def forward( + self, + inputs: torch.Tensor | None = None, + attention_mask: torch.Tensor | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + labels: torch.Tensor | None = None, + return_dict: bool | None = None, + input_ids: torch.Tensor | None = None, + **kwargs, + ) -> tuple | PerceiverMaskedLMOutput: + r""" + inputs (`torch.FloatTensor`): + Inputs to the perceiver. Can be anything: images, text, audio, video, etc. + labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Labels for computing the masked language modeling loss. Indices should be in `[-100, 0, ..., + config.vocab_size]` (see `input_ids` docstring) Tokens with indices set to `-100` are ignored (masked), the + loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]` + + Examples: + + ```python + >>> from transformers import AutoTokenizer, PerceiverForMaskedLM + >>> import torch + + >>> tokenizer = AutoTokenizer.from_pretrained("deepmind/language-perceiver") + >>> model = PerceiverForMaskedLM.from_pretrained("deepmind/language-perceiver") + + >>> # training + >>> text = "This is an incomplete sentence where some words are missing." + >>> inputs = tokenizer(text, padding="max_length", return_tensors="pt") + >>> # mask " missing." + >>> inputs["input_ids"][0, 52:61] = tokenizer.mask_token_id + >>> labels = tokenizer(text, padding="max_length", return_tensors="pt").input_ids + + >>> outputs = model(**inputs, labels=labels) + >>> loss = outputs.loss + >>> round(loss.item(), 2) + 19.87 + + >>> logits = outputs.logits + >>> list(logits.shape) + [1, 2048, 262] + + >>> # inference + >>> text = "This is an incomplete sentence where some words are missing." + >>> encoding = tokenizer(text, padding="max_length", return_tensors="pt") + + >>> # mask bytes corresponding to " missing.". Note that the model performs much better if the masked span starts with a space. + >>> encoding["input_ids"][0, 52:61] = tokenizer.mask_token_id + + >>> # forward pass + >>> with torch.no_grad(): + ... outputs = model(**encoding) + >>> logits = outputs.logits + >>> list(logits.shape) + [1, 2048, 262] + + >>> masked_tokens_predictions = logits[0, 52:61].argmax(dim=-1).tolist() + >>> tokenizer.decode(masked_tokens_predictions) + ' missing.' + ```""" + if inputs is not None and input_ids is not None: + raise ValueError("You cannot use both `inputs` and `input_ids`") + elif inputs is None and input_ids is not None: + inputs = input_ids + + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + outputs = self.perceiver( + inputs=inputs, + attention_mask=attention_mask, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + + logits = self.embedding_decoder( + outputs.logits if return_dict else outputs[0], embedding_layer=self.perceiver.input_preprocessor.embeddings + ) + + masked_lm_loss = None + if labels is not None: + loss_fct = CrossEntropyLoss() # -100 index = padding token + masked_lm_loss = loss_fct(logits.view(-1, self.config.vocab_size), labels.view(-1)) + + if not return_dict: + output = (logits,) + outputs[2:] + return ((masked_lm_loss,) + output) if masked_lm_loss is not None else output + + return PerceiverMaskedLMOutput( + loss=masked_lm_loss, + logits=logits, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + cross_attentions=outputs.cross_attentions, + ) + + +@auto_docstring( + custom_intro=""" + Example use of Perceiver for text classification. + """ +) +class PerceiverForSequenceClassification(PerceiverPreTrainedModel): + def __init__(self, config): + super().__init__(config) + + trainable_position_encoding_kwargs_decoder = {"num_channels": config.d_latents, "index_dims": 1} + + self.num_labels = config.num_labels + self.perceiver = PerceiverModel( + config, + input_preprocessor=PerceiverTextPreprocessor(config), + decoder=PerceiverClassificationDecoder( + config, + num_channels=config.d_latents, + trainable_position_encoding_kwargs=trainable_position_encoding_kwargs_decoder, + use_query_residual=True, + ), + ) + + # Initialize weights and apply final processing + self.post_init() + + @auto_docstring + def forward( + self, + inputs: torch.Tensor | None = None, + attention_mask: torch.Tensor | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + labels: torch.Tensor | None = None, + return_dict: bool | None = None, + input_ids: torch.Tensor | None = None, + **kwargs, + ) -> tuple | PerceiverClassifierOutput: + r""" + inputs (`torch.FloatTensor`): + Inputs to the perceiver. Can be anything: images, text, audio, video, etc. + labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*): + Labels for computing the classification/regression loss. Indices should be in `[0, ..., config.num_labels - + 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If `config.num_labels > + 1` a classification loss is computed (Cross-Entropy). + + Examples: + + ```python + >>> from transformers import AutoTokenizer, PerceiverForSequenceClassification + + >>> tokenizer = AutoTokenizer.from_pretrained("deepmind/language-perceiver") + >>> model = PerceiverForSequenceClassification.from_pretrained("deepmind/language-perceiver") + + >>> text = "hello world" + >>> inputs = tokenizer(text, return_tensors="pt").input_ids + >>> outputs = model(inputs=inputs) + >>> logits = outputs.logits + >>> list(logits.shape) + [1, 2] + ```""" + if inputs is not None and input_ids is not None: + raise ValueError("You cannot use both `inputs` and `input_ids`") + elif inputs is None and input_ids is not None: + inputs = input_ids + + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + outputs = self.perceiver( + inputs=inputs, + attention_mask=attention_mask, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + + logits = outputs.logits if return_dict else outputs[0] + + loss = None + if labels is not None: + if self.config.problem_type is None: + if self.num_labels == 1: + self.config.problem_type = "regression" + elif self.num_labels > 1 and (labels.dtype == torch.long or labels.dtype == torch.int): + self.config.problem_type = "single_label_classification" + else: + self.config.problem_type = "multi_label_classification" + + if self.config.problem_type == "regression": + loss_fct = MSELoss() + if self.num_labels == 1: + loss = loss_fct(logits.squeeze(), labels.squeeze()) + else: + loss = loss_fct(logits, labels) + elif self.config.problem_type == "single_label_classification": + loss_fct = CrossEntropyLoss() + loss = loss_fct(logits.view(-1, self.num_labels), labels.view(-1)) + elif self.config.problem_type == "multi_label_classification": + loss_fct = BCEWithLogitsLoss() + loss = loss_fct(logits, labels) + + if not return_dict: + output = (logits,) + outputs[2:] + return ((loss,) + output) if loss is not None else output + + return PerceiverClassifierOutput( + loss=loss, + logits=logits, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + cross_attentions=outputs.cross_attentions, + ) + + +@auto_docstring( + custom_intro=""" + Example use of Perceiver for image classification, for tasks such as ImageNet. + + This model uses learned position embeddings. In other words, this model is not given any privileged information about + the structure of images. As shown in the paper, this model can achieve a top-1 accuracy of 72.7 on ImageNet. + + [`PerceiverForImageClassificationLearned`] uses [`~models.perceiver.modeling_perceiver.PerceiverImagePreprocessor`] + (with `prep_type="conv1x1"`) to preprocess the input images, and + [`~models.perceiver.modeling_perceiver.PerceiverClassificationDecoder`] to decode the latent representation of + [`PerceiverModel`] into classification logits. + """ +) +class PerceiverForImageClassificationLearned(PerceiverPreTrainedModel): + def __init__(self, config): + super().__init__(config) + + trainable_position_encoding_kwargs_preprocessor = {"num_channels": 256, "index_dims": config.image_size**2} + trainable_position_encoding_kwargs_decoder = {"num_channels": config.d_latents, "index_dims": 1} + + self.num_labels = config.num_labels + self.perceiver = PerceiverModel( + config, + input_preprocessor=PerceiverImagePreprocessor( + config, + prep_type="conv1x1", + spatial_downsample=1, + out_channels=256, + position_encoding_type="trainable", + concat_or_add_pos="concat", + project_pos_dim=256, + trainable_position_encoding_kwargs=trainable_position_encoding_kwargs_preprocessor, + ), + decoder=PerceiverClassificationDecoder( + config, + num_channels=config.d_latents, + trainable_position_encoding_kwargs=trainable_position_encoding_kwargs_decoder, + use_query_residual=True, + ), + ) + + # Initialize weights and apply final processing + self.post_init() + + @auto_docstring + def forward( + self, + inputs: torch.Tensor | None = None, + attention_mask: torch.Tensor | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + labels: torch.Tensor | None = None, + interpolate_pos_encoding: bool = False, + return_dict: bool | None = None, + pixel_values: torch.Tensor | None = None, + **kwargs, + ) -> tuple | PerceiverClassifierOutput: + r""" + inputs (`torch.FloatTensor`): + Inputs to the perceiver. Can be anything: images, text, audio, video, etc. + labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*): + Labels for computing the image classification/regression loss. Indices should be in `[0, ..., + config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If + `config.num_labels > 1` a classification loss is computed (Cross-Entropy). + + Examples: + + ```python + >>> from transformers import AutoImageProcessor, PerceiverForImageClassificationLearned + >>> from PIL import Image + >>> import httpx + >>> from io import BytesIO + + >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg" + >>> with httpx.stream("GET", url) as response: + ... image = Image.open(BytesIO(response.read())) + + >>> image_processor = AutoImageProcessor.from_pretrained("deepmind/vision-perceiver-learned") + >>> model = PerceiverForImageClassificationLearned.from_pretrained("deepmind/vision-perceiver-learned") + + >>> inputs = image_processor(images=image, return_tensors="pt").pixel_values + >>> outputs = model(inputs=inputs) + >>> logits = outputs.logits + >>> list(logits.shape) + [1, 1000] + + >>> # model predicts one of the 1000 ImageNet classes + >>> predicted_class_idx = logits.argmax(-1).item() + >>> print("Predicted class:", model.config.id2label[predicted_class_idx]) + Predicted class: tabby, tabby cat + ```""" + if inputs is not None and pixel_values is not None: + raise ValueError("You cannot use both `inputs` and `pixel_values`") + elif inputs is None and pixel_values is not None: + inputs = pixel_values + + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + outputs = self.perceiver( + inputs=inputs, + attention_mask=attention_mask, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + interpolate_pos_encoding=interpolate_pos_encoding, + return_dict=return_dict, + ) + logits = outputs.logits if return_dict else outputs[0] + + loss = None + if labels is not None: + loss = self.loss_function(labels, logits, self.config) + + if not return_dict: + output = (logits,) + outputs[2:] + return ((loss,) + output) if loss is not None else output + + return PerceiverClassifierOutput( + loss=loss, + logits=logits, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + cross_attentions=outputs.cross_attentions, + ) + + +@auto_docstring( + custom_intro=""" + Example use of Perceiver for image classification, for tasks such as ImageNet. + + This model uses fixed 2D Fourier position embeddings. As shown in the paper, this model can achieve a top-1 accuracy of + 79.0 on ImageNet, and 84.5 when pre-trained on a large-scale dataset (i.e. JFT). + + [`PerceiverForImageClassificationLearned`] uses [`~models.perceiver.modeling_perceiver.PerceiverImagePreprocessor`] + (with `prep_type="pixels"`) to preprocess the input images, and + [`~models.perceiver.modeling_perceiver.PerceiverClassificationDecoder`] to decode the latent representation of + [`PerceiverModel`] into classification logits. + """ +) +class PerceiverForImageClassificationFourier(PerceiverPreTrainedModel): + def __init__(self, config): + super().__init__(config) + + fourier_position_encoding_kwargs_preprocessor = { + "concat_pos": True, + "max_resolution": (224, 224), + "num_bands": 64, + "sine_only": False, + } + trainable_position_encoding_kwargs_decoder = {"num_channels": config.d_latents, "index_dims": 1} + + self.num_labels = config.num_labels + self.perceiver = PerceiverModel( + config, + input_preprocessor=PerceiverImagePreprocessor( + config, + prep_type="pixels", + spatial_downsample=1, + fourier_position_encoding_kwargs=fourier_position_encoding_kwargs_preprocessor, + ), + decoder=PerceiverClassificationDecoder( + config, + num_channels=config.d_latents, + trainable_position_encoding_kwargs=trainable_position_encoding_kwargs_decoder, + use_query_residual=True, + ), + ) + + # Initialize weights and apply final processing + self.post_init() + + @auto_docstring + def forward( + self, + inputs: torch.Tensor | None = None, + attention_mask: torch.Tensor | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + labels: torch.Tensor | None = None, + return_dict: bool | None = None, + pixel_values: torch.Tensor | None = None, + **kwargs, + ) -> tuple | PerceiverClassifierOutput: + r""" + inputs (`torch.FloatTensor`): + Inputs to the perceiver. Can be anything: images, text, audio, video, etc. + labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*): + Labels for computing the image classification/regression loss. Indices should be in `[0, ..., + config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If + `config.num_labels > 1` a classification loss is computed (Cross-Entropy). + + Examples: + + ```python + >>> from transformers import AutoImageProcessor, PerceiverForImageClassificationFourier + >>> from PIL import Image + >>> import httpx + >>> from io import BytesIO + + >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg" + >>> with httpx.stream("GET", url) as response: + ... image = Image.open(BytesIO(response.read())) + + >>> image_processor = AutoImageProcessor.from_pretrained("deepmind/vision-perceiver-fourier") + >>> model = PerceiverForImageClassificationFourier.from_pretrained("deepmind/vision-perceiver-fourier") + + >>> inputs = image_processor(images=image, return_tensors="pt").pixel_values + >>> outputs = model(inputs=inputs) + >>> logits = outputs.logits + >>> list(logits.shape) + [1, 1000] + + >>> # model predicts one of the 1000 ImageNet classes + >>> predicted_class_idx = logits.argmax(-1).item() + >>> print("Predicted class:", model.config.id2label[predicted_class_idx]) + Predicted class: tabby, tabby cat + ```""" + if inputs is not None and pixel_values is not None: + raise ValueError("You cannot use both `inputs` and `pixel_values`") + elif inputs is None and pixel_values is not None: + inputs = pixel_values + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + outputs = self.perceiver( + inputs=inputs, + attention_mask=attention_mask, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + logits = outputs.logits if return_dict else outputs[0] + + loss = None + if labels is not None: + loss = self.loss_function(labels, logits, self.config) + + if not return_dict: + output = (logits,) + outputs[2:] + return ((loss,) + output) if loss is not None else output + + return PerceiverClassifierOutput( + loss=loss, + logits=logits, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + cross_attentions=outputs.cross_attentions, + ) + + +@auto_docstring( + custom_intro=""" + Example use of Perceiver for image classification, for tasks such as ImageNet. + + This model uses a 2D conv+maxpool preprocessing network. As shown in the paper, this model can achieve a top-1 accuracy + of 82.1 on ImageNet. + + [`PerceiverForImageClassificationLearned`] uses [`~models.perceiver.modeling_perceiver.PerceiverImagePreprocessor`] + (with `prep_type="conv"`) to preprocess the input images, and + [`~models.perceiver.modeling_perceiver.PerceiverClassificationDecoder`] to decode the latent representation of + [`PerceiverModel`] into classification logits. + """ +) +class PerceiverForImageClassificationConvProcessing(PerceiverPreTrainedModel): + def __init__(self, config): + super().__init__(config) + + fourier_position_encoding_kwargs_preprocessor = { + "concat_pos": True, + "max_resolution": (56, 56), + "num_bands": 64, + "sine_only": False, + } + trainable_position_encoding_kwargs_decoder = {"num_channels": config.d_latents, "index_dims": 1} + + self.num_labels = config.num_labels + self.perceiver = PerceiverModel( + config, + input_preprocessor=PerceiverImagePreprocessor( + config, + prep_type="conv", + spatial_downsample=1, + position_encoding_type="fourier", + fourier_position_encoding_kwargs=fourier_position_encoding_kwargs_preprocessor, + ), + decoder=PerceiverClassificationDecoder( + config, + num_channels=config.d_latents, + trainable_position_encoding_kwargs=trainable_position_encoding_kwargs_decoder, + use_query_residual=True, + ), + ) + + # Initialize weights and apply final processing + self.post_init() + + @auto_docstring + def forward( + self, + inputs: torch.Tensor | None = None, + attention_mask: torch.Tensor | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + labels: torch.Tensor | None = None, + return_dict: bool | None = None, + pixel_values: torch.Tensor | None = None, + **kwargs, + ) -> tuple | PerceiverClassifierOutput: + r""" + inputs (`torch.FloatTensor`): + Inputs to the perceiver. Can be anything: images, text, audio, video, etc. + labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*): + Labels for computing the image classification/regression loss. Indices should be in `[0, ..., + config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If + `config.num_labels > 1` a classification loss is computed (Cross-Entropy). + + Examples: + + ```python + >>> from transformers import AutoImageProcessor, PerceiverForImageClassificationConvProcessing + >>> from PIL import Image + >>> import httpx + >>> from io import BytesIO + + >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg" + >>> with httpx.stream("GET", url) as response: + ... image = Image.open(BytesIO(response.read())) + + >>> image_processor = AutoImageProcessor.from_pretrained("deepmind/vision-perceiver-conv") + >>> model = PerceiverForImageClassificationConvProcessing.from_pretrained("deepmind/vision-perceiver-conv") + + >>> inputs = image_processor(images=image, return_tensors="pt").pixel_values + >>> outputs = model(inputs=inputs) + >>> logits = outputs.logits + >>> list(logits.shape) + [1, 1000] + + >>> # model predicts one of the 1000 ImageNet classes + >>> predicted_class_idx = logits.argmax(-1).item() + >>> print("Predicted class:", model.config.id2label[predicted_class_idx]) + Predicted class: tabby, tabby cat + ```""" + if inputs is not None and pixel_values is not None: + raise ValueError("You cannot use both `inputs` and `pixel_values`") + elif inputs is None and pixel_values is not None: + inputs = pixel_values + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + outputs = self.perceiver( + inputs=inputs, + attention_mask=attention_mask, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + logits = outputs.logits if return_dict else outputs[0] + + loss = None + if labels is not None: + loss = self.loss_function(labels, logits, self.config) + + if not return_dict: + output = (logits,) + outputs[2:] + return ((loss,) + output) if loss is not None else output + + return PerceiverClassifierOutput( + loss=loss, + logits=logits, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + cross_attentions=outputs.cross_attentions, + ) + + +@auto_docstring( + custom_intro=""" + Example use of Perceiver for optical flow, for tasks such as Sintel and KITTI. [`PerceiverForOpticalFlow`] uses + [`~models.perceiver.modeling_perceiver.PerceiverImagePreprocessor`] (with *prep_type="patches"*) to preprocess the + input images, and [`~models.perceiver.modeling_perceiver.PerceiverOpticalFlowDecoder`] to decode the latent + representation of [`PerceiverModel`]. + + As input, one concatenates 2 subsequent frames along the channel dimension and extract a 3 x 3 patch around each pixel + (leading to 3 x 3 x 3 x 2 = 54 values for each pixel). Fixed Fourier position encodings are used to encode the position + of each pixel in the patch. Next, one applies the Perceiver encoder. To decode, one queries the latent representation + using the same encoding used for the input. + """ +) +class PerceiverForOpticalFlow(PerceiverPreTrainedModel): + def __init__(self, config): + super().__init__(config) + + fourier_position_encoding_kwargs_preprocessor = { + "num_bands": 64, + "max_resolution": config.train_size, + "sine_only": False, + "concat_pos": True, + } + fourier_position_encoding_kwargs_decoder = { + "concat_pos": True, + "max_resolution": config.train_size, + "num_bands": 64, + "sine_only": False, + } + + image_preprocessor = PerceiverImagePreprocessor( + config, + prep_type="patches", + spatial_downsample=1, + conv_after_patching=True, + conv_after_patching_in_channels=54, + temporal_downsample=2, + position_encoding_type="fourier", + # position_encoding_kwargs + fourier_position_encoding_kwargs=fourier_position_encoding_kwargs_preprocessor, + ) + + self.perceiver = PerceiverModel( + config, + input_preprocessor=image_preprocessor, + decoder=PerceiverOpticalFlowDecoder( + config, + num_channels=image_preprocessor.num_channels, + output_image_shape=config.train_size, + rescale_factor=100.0, + # decoder kwargs + use_query_residual=False, + output_num_channels=2, + # We query the decoder using the first frame features + # rather than a standard decoder position encoding. + position_encoding_type="fourier", + fourier_position_encoding_kwargs=fourier_position_encoding_kwargs_decoder, + ), + ) + + # Initialize weights and apply final processing + self.post_init() + + @auto_docstring + def forward( + self, + inputs: torch.Tensor | None = None, + attention_mask: torch.Tensor | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + labels: torch.Tensor | None = None, + return_dict: bool | None = None, + **kwargs, + ) -> tuple | PerceiverClassifierOutput: + r""" + inputs (`torch.FloatTensor`): + Inputs to the perceiver. Can be anything: images, text, audio, video, etc. + labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*): + Labels for computing the optical flow loss. Indices should be in `[0, ..., config.num_labels - 1]`. + + Examples: + + ```python + >>> from transformers import PerceiverForOpticalFlow + >>> import torch + + >>> model = PerceiverForOpticalFlow.from_pretrained("deepmind/optical-flow-perceiver") + + >>> # in the Perceiver IO paper, the authors extract a 3 x 3 patch around each pixel, + >>> # leading to 3 x 3 x 3 = 27 values for each pixel (as each pixel also has 3 color channels) + >>> # patches have shape (batch_size, num_frames, num_channels, height, width) + >>> # the authors train on resolutions of 368 x 496 + >>> patches = torch.randn(1, 2, 27, 368, 496) + >>> outputs = model(inputs=patches) + >>> logits = outputs.logits + >>> list(logits.shape) + [1, 368, 496, 2] + ```""" + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + loss = None + if labels is not None: + raise NotImplementedError("Optical flow training is not yet supported") + + outputs = self.perceiver( + inputs=inputs, + attention_mask=attention_mask, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + logits = outputs.logits if return_dict else outputs[0] + + if not return_dict: + output = (logits,) + outputs[2:] + return ((loss,) + output) if loss is not None else output + + return PerceiverClassifierOutput( + loss=loss, + logits=logits, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + cross_attentions=outputs.cross_attentions, + ) + + +@auto_docstring( + custom_intro=""" + Example use of Perceiver for multimodal (video) autoencoding, for tasks such as Kinetics-700. + + [`PerceiverForMultimodalAutoencoding`] uses [`~models.perceiver.modeling_perceiver.PerceiverMultimodalPreprocessor`] to + preprocess the 3 modalities: images, audio and class labels. This preprocessor uses modality-specific preprocessors to + preprocess every modality separately, after which they are concatenated. Trainable position embeddings are used to pad + each modality to the same number of channels to make concatenation along the time dimension possible. Next, one applies + the Perceiver encoder. + + [`~models.perceiver.modeling_perceiver.PerceiverMultimodalDecoder`] is used to decode the latent representation of + [`PerceiverModel`]. This decoder uses each modality-specific decoder to construct queries. The decoder queries are + created based on the inputs after preprocessing. However, autoencoding an entire video in a single forward pass is + computationally infeasible, hence one only uses parts of the decoder queries to do cross-attention with the latent + representation. This is determined by the subsampled indices for each modality, which can be provided as additional + input to the forward pass of [`PerceiverForMultimodalAutoencoding`]. + + [`~models.perceiver.modeling_perceiver.PerceiverMultimodalDecoder`] also pads the decoder queries of the different + modalities to the same number of channels, in order to concatenate them along the time dimension. Next, cross-attention + is performed with the latent representation of [`PerceiverModel`]. + + Finally, [`~models.perceiver.modeling_perceiver.PerceiverMultiModalPostprocessor`] is used to turn this tensor into an + actual video. It first splits up the output into the different modalities, and then applies the respective + postprocessor for each modality. + + Note that, by masking the classification label during evaluation (i.e. simply providing a tensor of zeros for the + "label" modality), this auto-encoding model becomes a Kinetics 700 video classifier. + """ +) +class PerceiverForMultimodalAutoencoding(PerceiverPreTrainedModel): + def __init__(self, config: PerceiverConfig): + super().__init__(config) + + n_audio_samples = config.num_frames * config.audio_samples_per_frame + + input_preprocessor = PerceiverMultimodalPreprocessor( + min_padding_size=4, + modalities={ + "audio": PerceiverAudioPreprocessor( + config, + position_encoding_type="fourier", + fourier_position_encoding_kwargs={ + "num_bands": 192, + "max_resolution": (n_audio_samples,), + "sine_only": False, + "concat_pos": True, + }, + prep_type="patches", + samples_per_patch=config.samples_per_patch, + ), + "image": PerceiverImagePreprocessor( + config, + position_encoding_type="fourier", + fourier_position_encoding_kwargs={ + "num_bands": 32, + "max_resolution": (config.num_frames, config.image_size, config.image_size), + "sine_only": False, + "concat_pos": True, + }, + prep_type="patches", + spatial_downsample=4, + temporal_downsample=1, + ), + "label": PerceiverOneHotPreprocessor(config), + }, + mask_probs={"image": 0.0, "audio": 0.0, "label": 1.0}, + ) + + image_decoder = PerceiverBasicVideoAutoencodingDecoder( + config, + # Autoencoding, don't pass inputs to the queries. + concat_preprocessed_input=False, + output_shape=config.output_shape, + output_num_channels=config.output_num_channels, + use_query_residual=False, + position_encoding_only=True, + position_encoding_type="fourier", + fourier_position_encoding_kwargs={ + "num_bands": 32, + "max_resolution": (config.num_frames, config.image_size, config.image_size), + "sine_only": False, + "concat_pos": True, + }, + ) + + decoder = PerceiverMultimodalDecoder( + config, + # Autoencoding, don't pass inputs to the queries. + concat_preprocessed_input=False, + # Modality specific decoders are used ONLY to generate queries. + # All modalties are decoded together using a unified decoder. + modalities={ + "audio": PerceiverBasicDecoder( + config, + # Autoencoding, don't pass inputs to the queries. + concat_preprocessed_input=False, + output_index_dims=(n_audio_samples // config.samples_per_patch,), + output_num_channels=config.output_num_channels, + use_query_residual=False, + position_encoding_only=True, + position_encoding_type="fourier", + fourier_position_encoding_kwargs={ + "num_bands": 192, + "max_resolution": (n_audio_samples,), + "sine_only": False, + "concat_pos": True, + }, + ), + "image": image_decoder, + "label": PerceiverClassificationDecoder( + config, + # Autoencoding, don't pass inputs to the queries. + concat_preprocessed_input=False, + use_query_residual=False, + position_encoding_only=True, + position_encoding_type="trainable", + trainable_position_encoding_kwargs={ + "num_channels": config._label_trainable_num_channels, + "index_dims": 1, + }, + ), + }, + num_outputs=None, + output_num_channels=config.output_num_channels, + use_query_residual=False, + ) + + output_postprocessor = PerceiverMultimodalPostprocessor( + modalities={ + "audio": PerceiverAudioPostprocessor(config, in_channels=config.output_num_channels), + "image": PerceiverProjectionPostprocessor(in_channels=config.output_num_channels, out_channels=3), + "label": PerceiverClassificationPostprocessor(config, in_channels=config.output_num_channels), + } + ) + + self.perceiver = PerceiverModel( + config, + input_preprocessor=input_preprocessor, + decoder=decoder, + output_postprocessor=output_postprocessor, + ) + + # Initialize weights and apply final processing + self.post_init() + + @auto_docstring + def forward( + self, + inputs: torch.Tensor | None = None, + attention_mask: torch.Tensor | None = None, + subsampled_output_points: dict[str, torch.Tensor] | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + labels: torch.Tensor | None = None, + return_dict: bool | None = None, + **kwargs, + ) -> tuple | PerceiverClassifierOutput: + r""" + inputs (`torch.FloatTensor`): + Inputs to the perceiver. Can be anything: images, text, audio, video, etc. + subsampled_output_points (`dict[str, torch.Tensor]`, *optional*): + Dictionary of tensors used as queries for the decoder. The decoder maps these queries to the latent + representation of the model. Used for subsampled decoding, e.g. when only decoding certain image patches. + labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*): + Labels for computing the image classification/regression loss. Indices should be in `[0, ..., + config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If + `config.num_labels > 1` a classification loss is computed (Cross-Entropy). + + Examples: + + ```python + >>> from transformers import PerceiverForMultimodalAutoencoding + >>> import torch + >>> import numpy as np + + >>> # create multimodal inputs + >>> images = torch.randn((1, 16, 3, 224, 224)) + >>> audio = torch.randn((1, 30720, 1)) + >>> inputs = dict(image=images, audio=audio, label=torch.zeros((images.shape[0], 700))) + + >>> model = PerceiverForMultimodalAutoencoding.from_pretrained("deepmind/multimodal-perceiver") + + >>> # in the Perceiver IO paper, videos are auto-encoded in chunks + >>> # each chunk subsamples different index dimensions of the image and audio modality decoder queries + >>> nchunks = 128 + >>> image_chunk_size = np.prod((16, 224, 224)) // nchunks + >>> audio_chunk_size = audio.shape[1] // model.config.samples_per_patch // nchunks + >>> # process the first chunk + >>> chunk_idx = 0 + >>> subsampling = { + ... "image": torch.arange(image_chunk_size * chunk_idx, image_chunk_size * (chunk_idx + 1)), + ... "audio": torch.arange(audio_chunk_size * chunk_idx, audio_chunk_size * (chunk_idx + 1)), + ... "label": None, + ... } + + >>> outputs = model(inputs=inputs, subsampled_output_points=subsampling) + >>> logits = outputs.logits + >>> list(logits["audio"].shape) + [1, 240] + + >>> list(logits["image"].shape) + [1, 6272, 3] + + >>> list(logits["label"].shape) + [1, 700] + ```""" + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + loss = None + if labels is not None: + raise NotImplementedError("Multimodal autoencoding training is not yet supported") + + outputs = self.perceiver( + inputs=inputs, + attention_mask=attention_mask, + subsampled_output_points=subsampled_output_points, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + logits = outputs.logits if return_dict else outputs[0] + + if not return_dict: + output = (logits,) + outputs[2:] + return ((loss,) + output) if loss is not None else output + + return PerceiverClassifierOutput( + loss=loss, + logits=logits, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + cross_attentions=outputs.cross_attentions, + ) + + +# Below: position encodings + + +def build_position_encoding( + position_encoding_type, + out_channels=None, + project_pos_dim=-1, + trainable_position_encoding_kwargs=None, + fourier_position_encoding_kwargs=None, +): + """ + Builds the position encoding. + + Args: + - out_channels: refers to the number of channels of the position encodings. + - project_pos_dim: if specified, will project the position encodings to this dimension. + + """ + + if position_encoding_type == "trainable": + if not trainable_position_encoding_kwargs: + raise ValueError("Make sure to pass trainable_position_encoding_kwargs") + output_pos_enc = PerceiverTrainablePositionEncoding(**trainable_position_encoding_kwargs) + elif position_encoding_type == "fourier": + # We don't use the index_dims argument, as this is only known during the forward pass + if not fourier_position_encoding_kwargs: + raise ValueError("Make sure to pass fourier_position_encoding_kwargs") + output_pos_enc = PerceiverFourierPositionEncoding(**fourier_position_encoding_kwargs) + else: + raise ValueError(f"Unknown position encoding type: {position_encoding_type}.") + + # Optionally, project the position encoding to a target dimension: + positions_projection = nn.Linear(out_channels, project_pos_dim) if project_pos_dim > 0 else nn.Identity() + + return output_pos_enc, positions_projection + + +# Below: Perceiver decoders + + +class PerceiverAbstractDecoder(nn.Module, metaclass=abc.ABCMeta): + """Perceiver abstract decoder.""" + + @abc.abstractmethod + def decoder_query(self, inputs, modality_sizes=None, inputs_without_pos=None, subsampled_points=None): + raise NotImplementedError + + @property + @abc.abstractmethod + def num_query_channels(self): + raise NotImplementedError + + @abc.abstractmethod + def forward(self, query, z, query_mask=None): + raise NotImplementedError + + +class PerceiverProjectionDecoder(PerceiverAbstractDecoder): + """ + Baseline projection decoder (no cross-attention). + + Args: + config ([`PerceiverConfig`]): + Model configuration. + """ + + def __init__(self, config): + super().__init__() + self.classifier = nn.Linear(config.d_latents, config.num_labels) + + def decoder_query(self, inputs, modality_sizes=None, inputs_without_pos=None, subsampled_points=None): + return None + + def forward( + self, query: torch.Tensor, z: torch.FloatTensor, query_mask: torch.FloatTensor | None = None + ) -> torch.FloatTensor: + # (batch_size, num_latents, d_latents) -> (batch_size, d_latents) + z = torch.mean(z, dim=1) + # (batch_size, d_latents) -> (batch_size, config.num_labels) + logits = self.classifier(z) + return logits + + +class PerceiverBasicDecoder(PerceiverAbstractDecoder): + """ + Cross-attention-based decoder. This class can be used to decode the final hidden states of the latents using a + cross-attention operation, in which the latents produce keys and values. + + The shape of the output of this class depends on how one defines the output queries (also called decoder queries). + + Args: + config ([*PerceiverConfig*]): + Model configuration. + output_num_channels (`int`, *optional*): + The number of channels in the output. Will only be used in case *final_project* is set to `True`. + position_encoding_type (`str`, *optional*, defaults to "trainable"): + The type of position encoding to use. Can be either "trainable", "fourier", or "none". + output_index_dims (`int`, *optional*): + The number of dimensions of the output queries. Ignored if 'position_encoding_type' == 'none'. + num_channels (`int`, *optional*, defaults to 128): + The number of channels of the decoder queries. Ignored if 'position_encoding_type' == 'none'. + qk_channels (`int`, *optional*): + The number of channels of the queries and keys in the cross-attention layer. + v_channels (`int`, *optional*): + The number of channels of the values in the cross-attention layer. + num_heads (`int`, *optional*, defaults to 1): + The number of attention heads in the cross-attention layer. + widening_factor (`int`, *optional*, defaults to 1): + The widening factor of the cross-attention layer. + use_query_residual (`bool`, *optional*, defaults to `False`): + Whether to use a residual connection between the query and the output of the cross-attention layer. + concat_preprocessed_input (`bool`, *optional*, defaults to `False`): + Whether to concatenate the preprocessed input to the query. + final_project (`bool`, *optional*, defaults to `True`): + Whether to project the output of the cross-attention layer to a target dimension. + position_encoding_only (`bool`, *optional*, defaults to `False`): + Whether to only use this class to define output queries. + """ + + def __init__( + self, + config: PerceiverConfig, + output_num_channels: int, + position_encoding_type: str | None = "trainable", + # The following 2 arguments are ignored if position_encoding_type == 'none': + output_index_dims: int | None = None, + num_channels: int | None = 128, + subsampled_index_dims: int | None = None, + qk_channels: int | None = None, + v_channels: int | None = None, + num_heads: int | None = 1, + widening_factor: int | None = 1, + use_query_residual: bool | None = False, + concat_preprocessed_input: bool | None = False, + final_project: bool | None = True, + position_encoding_only: bool | None = False, + **position_encoding_kwargs, + ) -> None: + super().__init__() + + self.output_num_channels = output_num_channels + # If `none`, the decoder will not construct any position encodings. + # You should construct your own when querying the decoder. + self.output_position_encodings = None + self.position_encoding_type = position_encoding_type + self.position_encoding_kwargs = position_encoding_kwargs + if position_encoding_type != "none": + self.output_position_encodings, self.positions_projection = build_position_encoding( + position_encoding_type=position_encoding_type, **position_encoding_kwargs + ) + + self.output_index_dims = output_index_dims + self.num_channels = num_channels + if subsampled_index_dims is None: + subsampled_index_dims = output_index_dims + self.subsampled_index_dims = subsampled_index_dims + self.concat_preprocessed_input = concat_preprocessed_input + self.final_project = final_project + self.position_encoding_only = position_encoding_only + + # for multimodal autoencoding, we don't need the decoder cross-attention and final layer + # so then we will set position_encoding_only to True + if not self.position_encoding_only: + self.decoding_cross_attention = PerceiverLayer( + config, + is_cross_attention=True, + qk_channels=qk_channels, + v_channels=v_channels, + num_heads=num_heads, + q_dim=num_channels, + kv_dim=config.d_latents, + widening_factor=widening_factor, + use_query_residual=use_query_residual, + ) + self.final_layer = nn.Linear(num_channels, output_num_channels) if final_project else nn.Identity() + + @property + def num_query_channels(self) -> int: + if self.position_encoding_type == "none": # Queries come from elsewhere + raise ValueError( + "You cannot calculate number of decoder query channels when position_encoding_type is set to none" + ) + if self.position_encoding_only: + if "project_pos_dim" in self.position_encoding_kwargs: + return self.position_encoding_kwargs["project_pos_dim"] + return self.output_position_encodings.output_size() + if self.final_project: + return self.output_num_channels + return self.num_channels + + def decoder_query(self, inputs, modality_sizes=None, inputs_without_pos=None, subsampled_points=None): + if self.position_encoding_type == "none": # Queries come from elsewhere + raise ValueError("You cannot construct decoder queries when position_encoding_type is set to none") + if subsampled_points is not None: + # subsampled_points are the indices if the inputs would be flattened + # however, the inputs aren't flattened, that's why we use unravel_index + # to get the indices for the unflattened array + # unravel_index returns a tuple (x_idx, y_idx, ...) + # stack to get the [n, d] tensor of coordinates + indices = torch.unravel_index(subsampled_points, self.output_index_dims) + pos = torch.stack(indices, dim=1) + batch_size = inputs.shape[0] + # Map these coordinates to [-1, 1] + pos = -1 + 2 * pos / torch.tensor(self.output_index_dims)[None, :] + pos = torch.broadcast_to(pos[None], [batch_size, pos.shape[0], pos.shape[1]]) + # Construct the position encoding. + if self.position_encoding_type == "trainable": + pos_emb = self.output_position_encodings(batch_size) + elif self.position_encoding_type == "fourier": + pos_emb = self.output_position_encodings( + self.output_index_dims, batch_size=batch_size, device=inputs.device, dtype=inputs.dtype, pos=pos + ) + + # Optionally project them to a target dimension. + pos_emb = self.positions_projection(pos_emb) + pos_emb = torch.reshape(pos_emb, [pos_emb.shape[0], -1, pos_emb.shape[-1]]) + else: + batch_size = inputs.shape[0] + index_dims = inputs.shape[2:] + + # Construct the position encoding. + if self.position_encoding_type == "trainable": + pos_emb = self.output_position_encodings(batch_size) + elif self.position_encoding_type == "fourier": + pos_emb = self.output_position_encodings( + index_dims, batch_size, device=inputs.device, dtype=inputs.dtype + ) + + # Optionally project them to a target dimension. + pos_emb = self.positions_projection(pos_emb) + + if self.concat_preprocessed_input: + if inputs_without_pos is None: + raise ValueError("Value is required for inputs_without_pos if concat_preprocessed_input is True") + pos_emb = torch.cat([inputs_without_pos, pos_emb], dim=-1) + + return pos_emb + + def forward( + self, + query: torch.Tensor, + z: torch.FloatTensor, + query_mask: torch.FloatTensor | None = None, + output_attentions: bool | None = False, + ) -> PerceiverDecoderOutput: + # Cross-attention decoding. + # key, value: B x N x K; query: B x M x K + # Attention maps -> B x N x M + # Output -> B x M x K + cross_attentions = () if output_attentions else None + + layer_outputs = self.decoding_cross_attention( + query, + attention_mask=query_mask, + inputs=z, + inputs_mask=None, + output_attentions=output_attentions, + ) + output = layer_outputs[0] + + if output_attentions: + cross_attentions = cross_attentions + (layer_outputs[1],) + + logits = self.final_layer(output) + + return PerceiverDecoderOutput(logits=logits, cross_attentions=cross_attentions) + + +class PerceiverClassificationDecoder(PerceiverAbstractDecoder): + """ + Cross-attention based classification decoder. Light-weight wrapper of [`PerceiverBasicDecoder`] for logit output. + Will turn the output of the Perceiver encoder which is of shape (batch_size, num_latents, d_latents) to a tensor of + shape (batch_size, num_labels). The queries are of shape (batch_size, 1, num_labels). + + Args: + config ([`PerceiverConfig`]): + Model configuration. + """ + + def __init__(self, config, **decoder_kwargs): + super().__init__() + + self.num_labels = config.num_labels + self.decoder = PerceiverBasicDecoder( + config, + output_num_channels=self.num_labels, + output_index_dims=1, # Predict a single logit array. + **decoder_kwargs, + ) + + @property + def num_query_channels(self) -> int: + return self.decoder.num_query_channels + + def decoder_query(self, inputs, modality_sizes=None, inputs_without_pos=None, subsampled_points=None): + return self.decoder.decoder_query( + inputs, modality_sizes, inputs_without_pos, subsampled_points=subsampled_points + ) + + def forward( + self, + query: torch.Tensor, + z: torch.FloatTensor, + query_mask: torch.FloatTensor | None = None, + output_attentions: bool | None = False, + ) -> PerceiverDecoderOutput: + decoder_outputs = self.decoder(query, z, output_attentions=output_attentions) + + # B x 1 x num_classes -> B x num_classes + logits = decoder_outputs.logits[:, 0, :] + + return PerceiverDecoderOutput(logits=logits, cross_attentions=decoder_outputs.cross_attentions) + + +class PerceiverOpticalFlowDecoder(PerceiverAbstractDecoder): + """Cross-attention based optical flow decoder.""" + + def __init__(self, config, output_image_shape, output_num_channels=2, rescale_factor=100.0, **decoder_kwargs): + super().__init__() + + self.output_image_shape = output_image_shape + self.output_num_channels = output_num_channels + self.rescale_factor = rescale_factor + self.decoder = PerceiverBasicDecoder(config, output_num_channels=output_num_channels, **decoder_kwargs) + + @property + def num_query_channels(self) -> int: + return self.decoder.num_query_channels + + def decoder_query(self, inputs, modality_sizes=None, inputs_without_pos=None, subsampled_points=None): + if subsampled_points is not None: + raise ValueError("FlowDecoder doesn't support subsampling yet.") + return inputs + + def forward( + self, + query: torch.Tensor, + z: torch.FloatTensor, + query_mask: torch.FloatTensor | None = None, + output_attentions: bool | None = False, + ) -> PerceiverDecoderOutput: + decoder_outputs = self.decoder(query, z, output_attentions=output_attentions) + preds = decoder_outputs.logits + # Output flow and rescale. + preds /= self.rescale_factor + preds = preds.reshape([preds.shape[0]] + list(self.output_image_shape) + [preds.shape[-1]]) + return PerceiverDecoderOutput(logits=preds, cross_attentions=decoder_outputs.cross_attentions) + + +class PerceiverBasicVideoAutoencodingDecoder(PerceiverAbstractDecoder): + """ + Cross-attention based video-autoencoding decoder. Light-weight wrapper of [*PerceiverBasicDecoder*] with video + reshaping logic. + + Args: + config ([*PerceiverConfig*]): + Model configuration. + output_shape (`list[int]`): + Shape of the output as (batch_size, num_frames, height, width), excluding the channel dimension. + position_encoding_type (`str`): + The type of position encoding to use. Can be either "trainable", "fourier", or "none". + """ + + def __init__( + self, config: PerceiverConfig, output_shape: list[int], position_encoding_type: str, **decoder_kwargs + ) -> None: + super().__init__() + if len(output_shape) != 4: # B, T, H, W + raise ValueError(f"Expected rank 4 output_shape, got {output_shape}.") + # Build the decoder components: + self.output_shape = output_shape + self.output_num_channels = decoder_kwargs["output_num_channels"] + + self.decoder = PerceiverBasicDecoder( + config, + output_index_dims=self.output_shape[1:4], # T*H*W + position_encoding_type=position_encoding_type, + **decoder_kwargs, + ) + + @property + def num_query_channels(self) -> int: + return self.decoder.num_query_channels + + def decoder_query(self, inputs, modality_sizes=None, inputs_without_pos=None, subsampled_points=None): + return self.decoder.decoder_query( + inputs, + modality_sizes=modality_sizes, + inputs_without_pos=inputs_without_pos, + subsampled_points=subsampled_points, + ) + + def forward( + self, query: torch.Tensor, z: torch.FloatTensor, query_mask: torch.FloatTensor | None = None + ) -> PerceiverDecoderOutput: + decoder_outputs = self.decoder(query, z) + logits = decoder_outputs.logits + + logits = torch.reshape(logits, self.output_shape + [logits.shape[-1]]) + return PerceiverDecoderOutput(logits=logits, cross_attentions=decoder_outputs.cross_attentions) + + +def restructure(modality_sizes: ModalitySizeType, inputs: torch.Tensor) -> Mapping[str, torch.Tensor]: + """ + Partitions a [B, N, C] tensor into tensors for each modality. + + Args: + modality_sizes + dict specifying the size of the modality + inputs: + input tensor + + Returns: + dict mapping name of modality to its associated tensor. + """ + outputs = {} + index = 0 + # Apply a predictable ordering to the modalities + for modality in sorted(modality_sizes.keys()): + size = modality_sizes[modality] + inp = inputs[:, index : index + size] + index += size + outputs[modality] = inp + return outputs + + +class PerceiverMultimodalDecoder(PerceiverAbstractDecoder): + """ + Multimodal decoding by composing uni-modal decoders. The *modalities* argument of the constructor is a dictionary + mapping modality name to the decoder of that modality. That decoder will be used to construct queries for that + modality. Modality-specific queries are padded with trainable modality-specific parameters, after which they are + concatenated along the time dimension. + + Next, there is a shared cross attention operation across all modalities. + + Args: + config ([*PerceiverConfig*]): + Model configuration. + modalities (`dict[str, PerceiverAbstractDecoder]`): + Dictionary mapping modality name to the decoder of that modality. + num_outputs (`int`): + The number of outputs of the decoder. + output_num_channels (`int`): + The number of channels in the output. + min_padding_size (`int`, *optional*, defaults to 2): + The minimum padding size for all modalities. The final output will have num_channels equal to the maximum + channels across all modalities plus min_padding_size. + subsampled_index_dims (`dict[str, PerceiverAbstractDecoder]`, *optional*): + Dictionary mapping modality name to the subsampled index dimensions to use for the decoder query of that + modality. + """ + + def __init__( + self, + config: PerceiverConfig, + modalities: dict[str, PerceiverAbstractDecoder], + num_outputs: int, + output_num_channels: int, + min_padding_size: int | None = 2, + subsampled_index_dims: dict[str, PerceiverAbstractDecoder] | None = None, + **decoder_kwargs, + ) -> None: + super().__init__() + self.modalities = nn.ModuleDict(modalities) + self.subsampled_index_dims = subsampled_index_dims + self.min_padding_size = min_padding_size + self.output_num_channels = output_num_channels + self.num_outputs = num_outputs + self.decoder = PerceiverBasicDecoder( + config, + output_index_dims=(num_outputs,), + output_num_channels=output_num_channels, + position_encoding_type="none", + num_channels=self.num_query_channels, + **decoder_kwargs, + ) + self.padding = nn.ParameterDict( + { + modality: nn.Parameter(torch.randn(1, self.num_query_channels - decoder.num_query_channels)) + for modality, decoder in modalities.items() + } + ) + + @property + def num_query_channels(self) -> int: + max_channel_size = max(decoder.num_query_channels for _, decoder in self.modalities.items()) + common_channel_size = max_channel_size + self.min_padding_size + return common_channel_size + + def decoder_query(self, inputs, modality_sizes, inputs_without_pos=None, subsampled_points=None): + # Partition the flat inputs among the different modalities + inputs = restructure(modality_sizes, inputs) + + # Obtain modality-specific decoders' queries + subsampled_points = subsampled_points or {} + + decoder_queries = {} + for modality, decoder in self.modalities.items(): + # Get input_without_pos for this modality if it exists. + input_without_pos = None + if inputs_without_pos is not None: + input_without_pos = inputs_without_pos.get(modality, None) + query = decoder.decoder_query( + inputs=inputs[modality], + modality_sizes=None, + inputs_without_pos=input_without_pos, + subsampled_points=subsampled_points.get(modality, None), + ) + decoder_queries[modality] = query + + # Pad all queries with trainable position encodings to make them have the same channels + + def embed(modality, x): + x = torch.reshape(x, [x.shape[0], np.prod(x.shape[1:-1]), x.shape[-1]]) + pos = self.padding[modality] + pos = torch.broadcast_to(pos, [x.shape[0], x.shape[1], self.num_query_channels - x.shape[2]]) + return torch.cat([x, pos], dim=2) + + # Apply a predictable ordering to the modalities + return torch.cat( + [embed(modality, decoder_queries[modality]) for modality in sorted(self.modalities.keys())], dim=1 + ) + + def forward( + self, + query: torch.Tensor, + z: torch.FloatTensor, + query_mask: torch.FloatTensor | None = None, + output_attentions: bool | None = False, + ) -> torch.Tensor: + # B x 1 x num_classes -> B x num_classes + decoder_outputs = self.decoder(query, z, output_attentions=output_attentions) + + return decoder_outputs + + +# Below: IO pre- and post-processor classes for Perceiver. +def space_to_depth(frames: torch.Tensor, temporal_block_size: int = 1, spatial_block_size: int = 1) -> torch.Tensor: + """ + Space to depth transform. Rearranges blocks of spatial data, into depth. + + This function assumes the channels to be first, but will place the channels last after transformation. + """ + if len(frames.shape) == 4: + batch_size, num_channels, height, width = frames.shape + # split up dimensions (height by spatial_block_size, width by spatial_block_size) + frames = frames.view( + batch_size, + num_channels, + height // spatial_block_size, + spatial_block_size, + width // spatial_block_size, + spatial_block_size, + ) + # move blocks to last dimension: (batch_size, H//bs, W//bs, bs, bs, C) + frames = frames.permute(0, 2, 4, 3, 5, 1).contiguous() + # concatenate blocks along channel dimension: (batch_size, H//bs, W//bs, bs*bs*C) + frames = frames.view( + batch_size, + height // spatial_block_size, + width // spatial_block_size, + (spatial_block_size**2) * num_channels, + ) + return frames + elif len(frames.shape) == 5: + batch_size, time, num_channels, height, width = frames.shape + # split up dimensions (time by temporal_block_size, height by spatial_block_size, width by spatial_block_size) + frames = frames.view( + batch_size, + time // temporal_block_size, + temporal_block_size, + num_channels, + height // spatial_block_size, + spatial_block_size, + width // spatial_block_size, + spatial_block_size, + ) + # move blocks to last dimension: (batch_size, T//ts, H//bs, W//bs, ts, bs, bs, C) + frames = frames.permute(0, 1, 4, 6, 2, 5, 7, 3).contiguous() + # concatenate blocks along channel dimension: (batch_size, T//ts, H//bs, W//bs, ts*bs*bs*C) + frames = frames.view( + batch_size, + time // temporal_block_size, + height // spatial_block_size, + width // spatial_block_size, + temporal_block_size * (spatial_block_size**2) * num_channels, + ) + return frames + else: + raise ValueError( + "Frames should be of rank 4 (batch, channels, height, width)" + " or rank 5 (batch, time, channels, height, width)" + ) + + +class Conv2dSamePadding(nn.Conv2d): + """ + Conv2d layer with padding="same" support. Source: + https://gist.github.com/sumanmichael/4de9dee93f972d47c80c4ade8e149ea6 + """ + + def __init__(self, *args, **kwargs): + super().__init__(*args, **kwargs) + self.zero_pad_2d = nn.ZeroPad2d( + reduce(__add__, [(k // 2 + (k - 2 * (k // 2)) - 1, k // 2) for k in self.kernel_size[::-1]]) + ) + + def forward(self, input): + return self._conv_forward(self.zero_pad_2d(input), self.weight, self.bias) + + +class Conv2DDownsample(nn.Module): + """Downsamples 4x by applying a 2D convolution and doing max pooling.""" + + def __init__( + self, + num_layers: int = 1, + in_channels: int = 3, + out_channels: int = 64, + use_batchnorm: bool = True, + ): + """ + Constructs a Conv2DDownsample model. + + Args: + in_channels (`int`, *optional*, defaults to 3): + The number of input channels. + out_channels (`int`, *optional*, defaults to 64): + The number of conv output channels. + use_batchnorm (`bool`, *optional*, defaults to `True`): + Whether to use batchnorm. + """ + super().__init__() + + self.conv = Conv2dSamePadding( + in_channels=in_channels, out_channels=out_channels, kernel_size=7, stride=2, bias=False + ) + self.batchnorm = nn.BatchNorm2d(num_features=out_channels) if use_batchnorm else nn.Identity() + self.relu = nn.ReLU() + self.max_pool = nn.MaxPool2d(kernel_size=3, stride=2) + + def forward(self, inputs: torch.Tensor) -> torch.Tensor: + out = self.conv(inputs) + out = self.batchnorm(out) + out = self.relu(out) + out = self.max_pool(out) + return out + + +def generate_fourier_features(pos, num_bands, max_resolution=(224, 224), concat_pos=True, sine_only=False): + """ + Generate a Fourier frequency position encoding with linear spacing. + + Args: + pos (`torch.LongTensor` of shape `(batch_size, sequence_length, dim)`): + The Tensor containing the position of n points in d dimensional space. + num_bands (`int`): + The number of frequency bands (K) to use. + max_resolution (`tuple[int]`, *optional*, defaults to (224, 224)): + The maximum resolution (i.e. the number of pixels per dim). A tuple representing resolution for each dimension. + concat_pos (`bool`, *optional*, defaults to `True`): + Whether to concatenate the input position encoding to the Fourier features. + sine_only (`bool`, *optional*, defaults to `False`): + Whether to use a single phase (sin) or two (sin/cos) for each frequency band. + + Returns: + `torch.FloatTensor` of shape `(batch_size, sequence_length, n_channels)`: The Fourier position embeddings. If + `concat_pos` is `True` and `sine_only` is `False`, output dimensions are ordered as: [dim_1, dim_2, ..., dim_d, + sin(pi*f_1*dim_1), ..., sin(pi*f_K*dim_1), ..., sin(pi*f_1*dim_d), ..., sin(pi*f_K*dim_d), cos(pi*f_1*dim_1), + ..., cos(pi*f_K*dim_1), ..., cos(pi*f_1*dim_d), ..., cos(pi*f_K*dim_d)], where dim_i is pos[:, i] and f_k is the + kth frequency band. + """ + + batch_size = pos.shape[0] + + min_freq = 1.0 + # Nyquist frequency at the target resolution: + freq_bands = torch.stack( + [torch.linspace(start=min_freq, end=res / 2, steps=num_bands) for res in max_resolution], dim=0 + ) + + # Get frequency bands for each spatial dimension. + # Output is size [n, d * num_bands] + per_pos_features = pos[0, :, :][:, :, None] * freq_bands[None, :, :] + per_pos_features = torch.reshape(per_pos_features, [-1, np.prod(per_pos_features.shape[1:])]) + + if sine_only: + # Output is size [n, d * num_bands] + per_pos_features = torch.sin(np.pi * (per_pos_features)) + else: + # Output is size [n, 2 * d * num_bands] + per_pos_features = torch.cat( + [torch.sin(np.pi * per_pos_features), torch.cos(np.pi * per_pos_features)], dim=-1 + ) + # Concatenate the raw input positions. + if concat_pos: + # Adds d bands to the encoding. + per_pos_features = torch.cat([pos, per_pos_features.expand(batch_size, -1, -1)], dim=-1) + return per_pos_features + + +def build_linear_positions(index_dims, output_range=(-1.0, 1.0)): + """ + Generate an array of position indices for an N-D input array. + + Args: + index_dims (`list[int]`): + The shape of the index dimensions of the input array. + output_range (`tuple[float]`, *optional*, defaults to `(-1.0, 1.0)`): + The min and max values taken by each input index dimension. + + Returns: + `torch.FloatTensor` of shape `(index_dims[0], index_dims[1], .., index_dims[-1], N)`. + """ + + def _linspace(n_xels_per_dim): + return torch.linspace(start=output_range[0], end=output_range[1], steps=n_xels_per_dim, dtype=torch.float32) + + dim_ranges = [_linspace(n_xels_per_dim) for n_xels_per_dim in index_dims] + array_index_grid = torch.meshgrid(*dim_ranges, indexing="ij") + + return torch.stack(array_index_grid, dim=-1) + + +class PerceiverAbstractPositionEncoding(nn.Module, metaclass=abc.ABCMeta): + """Perceiver abstract position encoding.""" + + @property + @abc.abstractmethod + def num_dimensions(self) -> int: + raise NotImplementedError + + @abc.abstractmethod + def output_size(self, *args, **kwargs) -> int: + raise NotImplementedError + + @abc.abstractmethod + def forward(self, batch_size, pos): + raise NotImplementedError + + +class PerceiverTrainablePositionEncoding(PerceiverAbstractPositionEncoding): + """Trainable position encoding.""" + + def __init__(self, index_dims, num_channels=128): + super().__init__() + self._num_channels = num_channels + self._index_dims = index_dims + index_dim = np.prod(index_dims) + self.position_embeddings = nn.Parameter(torch.randn(index_dim, num_channels)) + + @property + def num_dimensions(self) -> int: + if isinstance(self._index_dims, int): + return 1 + return len(self._index_dims) + + def output_size(self, *args, **kwargs) -> int: + return self._num_channels + + def interpolate_pos_encoding(self, position_embeddings: torch.Tensor, height: int, width: int) -> torch.Tensor: + num_positions = position_embeddings.shape[0] + new_height = new_width = torch_int(num_positions**0.5) + + # always interpolate when tracing to ensure the exported model works for dynamic input shapes + if not torch.jit.is_tracing() and height == new_height and width == new_width: + return position_embeddings + + position_embeddings = position_embeddings.reshape(1, new_height, new_width, self._num_channels).permute( + 0, 3, 1, 2 + ) + + position_embeddings = nn.functional.interpolate( + position_embeddings, + size=(new_height, new_width), + mode="bicubic", + align_corners=False, + ) + position_embeddings = position_embeddings.reshape(1, self._num_channels, -1).permute(0, 2, 1).squeeze(0) + return position_embeddings + + def forward( + self, batch_size: int, interpolate_pos_encoding: bool = False, input_size: torch.Size | None = None + ) -> torch.Tensor: + position_embeddings = self.position_embeddings + + if interpolate_pos_encoding: + height, width = input_size + position_embeddings = self.interpolate_pos_encoding(position_embeddings, height, width) + + if batch_size is not None: + position_embeddings = position_embeddings.expand(batch_size, -1, -1) + return position_embeddings + + +def _check_or_build_spatial_positions(pos, index_dims, batch_size): + """ + Checks or builds spatial position features (x, y, ...). + + Args: + pos (`torch.FloatTensor`): + None, or an array of position features. If None, position features are built. Otherwise, their size is checked. + index_dims (`list[int]`): + An iterable giving the spatial/index size of the data to be featurized. + batch_size (`int`): + The batch size of the data to be featurized. + + Returns: + `torch.FloatTensor` of shape `(batch_size, prod(index_dims))` an array of position features. + """ + if pos is None: + pos = build_linear_positions(index_dims) + # equivalent to `torch.broadcast_to(pos[None], (batch_size,) + pos.shape)` + # but `torch.broadcast_to` cannot be converted to ONNX + pos = pos[None].expand((batch_size,) + pos.shape) + pos = torch.reshape(pos, [batch_size, np.prod(index_dims), -1]) + else: + # Just a warning label: you probably don't want your spatial features to + # have a different spatial layout than your pos coordinate system. + # But feel free to override if you think it'll work! + if pos.shape[-1] != len(index_dims): + raise ValueError("Spatial features have the wrong number of dimensions.") + return pos + + +class PerceiverFourierPositionEncoding(PerceiverAbstractPositionEncoding): + """Fourier (Sinusoidal) position encoding.""" + + def __init__(self, num_bands, max_resolution, concat_pos=True, sine_only=False): + super().__init__() + self.num_bands = num_bands + self.max_resolution = max_resolution + self.concat_pos = concat_pos + self.sine_only = sine_only + + @property + def num_dimensions(self) -> int: + return len(self.max_resolution) + + def output_size(self): + """Returns size of positional encodings last dimension.""" + num_dims = len(self.max_resolution) + encoding_size = self.num_bands * num_dims + if not self.sine_only: + encoding_size *= 2 + if self.concat_pos: + encoding_size += self.num_dimensions + + return encoding_size + + def forward( + self, + index_dims: list[int], + batch_size: int, + device: torch.device, + dtype: torch.dtype, + pos: torch.FloatTensor | None = None, + ) -> torch.FloatTensor: + pos = _check_or_build_spatial_positions(pos, index_dims, batch_size) + fourier_pos_enc = generate_fourier_features( + pos, + num_bands=self.num_bands, + max_resolution=self.max_resolution, + concat_pos=self.concat_pos, + sine_only=self.sine_only, + ).to(device=device, dtype=dtype) + return fourier_pos_enc + + +class AbstractPreprocessor(nn.Module): + @property + def num_channels(self) -> int: + """Returns size of preprocessor output.""" + raise NotImplementedError() + + +class PerceiverTextPreprocessor(AbstractPreprocessor): + """ + Text preprocessing for Perceiver Encoder. Can be used to embed `inputs` and add positional encodings. + + The dimensionality of the embeddings is determined by the `d_model` attribute of the configuration. + + Args: + config ([`PerceiverConfig`]): + Model configuration. + """ + + def __init__(self, config: PerceiverConfig) -> None: + super().__init__() + self.config = config + self.embeddings = nn.Embedding(num_embeddings=config.vocab_size, embedding_dim=config.d_model) + self.position_embeddings = nn.Embedding(config.max_position_embeddings, config.d_model) + + @property + def num_channels(self) -> int: + return self.config.d_model + + def forward( + self, + inputs: torch.LongTensor, + pos: torch.Tensor | None = None, + network_input_is_1d: bool = True, + interpolate_pos_encoding: bool = False, + ): + embeddings_without_pos = self.embeddings(inputs) + + seq_length = inputs.shape[1] + position_ids = torch.arange(0, seq_length, device=inputs.device) + embeddings = embeddings_without_pos + self.position_embeddings(position_ids) + + return embeddings, None, embeddings_without_pos + + +class PerceiverEmbeddingDecoder(nn.Module): + """ + Module to decode embeddings (for masked language modeling). + + Args: + config ([`PerceiverConfig`]): + Model configuration. + """ + + def __init__(self, config: PerceiverConfig) -> None: + super().__init__() + self.config = config + self.vocab_size = config.vocab_size + self.bias = nn.Parameter(torch.zeros(self.vocab_size)) + + def forward(self, hidden_states: torch.Tensor, embedding_layer: torch.Tensor) -> torch.Tensor: + batch_size, seq_len, d_model = hidden_states.shape + # Flatten batch dim + output = torch.matmul(hidden_states.reshape([-1, d_model]), embedding_layer.weight.transpose(0, 1)) + output = output + self.bias + + return output.reshape([batch_size, seq_len, self.vocab_size]) + + +class PerceiverMultimodalPostprocessor(nn.Module): + """ + Multimodal postprocessing for Perceiver. Can be used to combine modality-specific postprocessors into a single + postprocessor. + + Args: + modalities (`Mapping[str, PostprocessorType]`): + Dictionary mapping modality name to postprocessor class for that modality. + input_is_dict (`bool`, *optional*, defaults to `False`): + If True, input is assumed to be dictionary structured, and outputs keep the same dictionary shape. If + False, input is a tensor which is sliced up during postprocessing by *modality_sizes*. + """ + + def __init__(self, modalities: Mapping[str, PostprocessorType], input_is_dict: bool = False): + super().__init__() + self.modalities = nn.ModuleDict(modalities) + self.input_is_dict = input_is_dict + + def forward( + self, inputs: torch.Tensor, pos: torch.Tensor | None = None, modality_sizes=None + ) -> Mapping[str, torch.Tensor]: + if not self.input_is_dict: + # Slice up modalities by their sizes. + if modality_sizes is None: + raise ValueError("Modality sizes should be specified if input is not a dictionary.") + inputs = restructure(modality_sizes=modality_sizes, inputs=inputs) + + outputs = { + modality: postprocessor(inputs[modality], pos=pos, modality_sizes=None) + for modality, postprocessor in self.modalities.items() + } + return outputs + + +class PerceiverClassificationPostprocessor(nn.Module): + """ + Classification postprocessing for Perceiver. Can be used to convert the decoder output to classification logits. + + Args: + config ([*PerceiverConfig*]): + Model configuration. + in_channels (`int`): + Number of channels in the input. + """ + + def __init__(self, config: PerceiverConfig, in_channels: int) -> None: + super().__init__() + self.classifier = nn.Linear(in_channels, config.num_labels) + + def forward(self, inputs, pos: torch.Tensor | None = None, modality_sizes=None) -> torch.Tensor: + logits = self.classifier(inputs) + return logits[:, 0, :] + + +class PerceiverAudioPostprocessor(nn.Module): + """ + Audio postprocessing for Perceiver. Can be used to convert the decoder output to audio features. + + Args: + config ([*PerceiverConfig*]): + Model configuration. + in_channels (`int`): + Number of channels in the input. + postproc_type (`str`, *optional*, defaults to `"patches"`): + Postprocessor type to use. Currently, only "patches" is supported. + """ + + def __init__(self, config: PerceiverConfig, in_channels: int, postproc_type: str = "patches") -> None: + super().__init__() + + if postproc_type != "patches": # to be supported: 'conv', 'patches', 'pixels' + raise ValueError("Invalid postproc_type!") + + # Architecture parameters: + self.classifier = nn.Linear(in_channels, config.samples_per_patch) + + def forward(self, inputs: torch.Tensor, pos: torch.Tensor | None = None, modality_sizes=None) -> torch.Tensor: + logits = self.classifier(inputs) + return torch.reshape(logits, [inputs.shape[0], -1]) + + +class PerceiverProjectionPostprocessor(nn.Module): + """ + Projection postprocessing for Perceiver. Can be used to project the channels of the decoder output to a lower + dimension. + + Args: + in_channels (`int`): + Number of channels in the input. + out_channels (`int`): + Number of channels in the output. + """ + + def __init__(self, in_channels: int, out_channels: int) -> None: + super().__init__() + self.classifier = nn.Linear(in_channels, out_channels) + + def forward(self, inputs: torch.Tensor, pos: torch.Tensor | None = None, modality_sizes=None) -> torch.Tensor: + logits = self.classifier(inputs) + return logits + + +class PerceiverImagePreprocessor(AbstractPreprocessor): + """ + Image preprocessing for Perceiver Encoder. + + Note: the *out_channels* argument refers to the output channels of a convolutional layer, if *prep_type* is set to + "conv1x1" or "conv". If one adds absolute position embeddings, one must make sure the *num_channels* of the + position encoding kwargs are set equal to the *out_channels*. + + Args: + config ([*PerceiverConfig*]): + Model configuration. + prep_type (`str`, *optional*, defaults to `"conv"`): + Preprocessing type. Can be "conv1x1", "conv", "patches", "pixels". + spatial_downsample (`int`, *optional*, defaults to 4): + Spatial downsampling factor. + temporal_downsample (`int`, *optional*, defaults to 1): + Temporal downsampling factor (only relevant in case a time dimension is present). + position_encoding_type (`str`, *optional*, defaults to `"fourier"`): + Position encoding type. Can be "fourier" or "trainable". + in_channels (`int`, *optional*, defaults to 3): + Number of channels in the input. + out_channels (`int`, *optional*, defaults to 64): + Number of channels in the output. + conv_after_patching (`bool`, *optional*, defaults to `False`): + Whether to apply a convolutional layer after patching. + conv_after_patching_in_channels (`int`, *optional*, defaults to 54): + Number of channels in the input of the convolutional layer after patching. + conv2d_use_batchnorm (`bool`, *optional*, defaults to `True`): + Whether to use batch normalization in the convolutional layer. + concat_or_add_pos (`str`, *optional*, defaults to `"concat"`): + How to concatenate the position encoding to the input. Can be "concat" or "add". + project_pos_dim (`int`, *optional*, defaults to -1): + Dimension of the position encoding to project to. If -1, no projection is applied. + **position_encoding_kwargs (`Dict`, *optional*): + Keyword arguments for the position encoding. + """ + + def __init__( + self, + config, + prep_type="conv", + spatial_downsample: int = 4, + temporal_downsample: int = 1, + position_encoding_type: str = "fourier", + in_channels: int = 3, + out_channels: int = 64, + conv_after_patching: bool = False, + conv_after_patching_in_channels: int = 54, # only relevant when conv_after_patching = True + conv2d_use_batchnorm: bool = True, + concat_or_add_pos: str = "concat", + project_pos_dim: int = -1, + **position_encoding_kwargs, + ): + super().__init__() + self.config = config + + if prep_type not in ("conv", "patches", "pixels", "conv1x1"): + raise ValueError(f"Prep_type {prep_type} is invalid") + + if concat_or_add_pos not in ["concat", "add"]: + raise ValueError(f"Invalid value {concat_or_add_pos} for concat_or_add_pos.") + + self.in_channels = in_channels + self.prep_type = prep_type + self.spatial_downsample = spatial_downsample + self.temporal_downsample = temporal_downsample + self.position_encoding_type = position_encoding_type + self.concat_or_add_pos = concat_or_add_pos + self.conv_after_patching = conv_after_patching + self.out_channels = out_channels + + if self.prep_type == "conv": + # Downsampling with conv is currently restricted + convnet_num_layers = math.log(spatial_downsample, 4) + convnet_num_layers_is_int = convnet_num_layers == np.round(convnet_num_layers) + if not convnet_num_layers_is_int or temporal_downsample != 1: + raise ValueError( + "Only powers of 4 expected for spatial and 1 expected for temporal downsampling with conv." + ) + self.convnet = Conv2DDownsample( + in_channels=in_channels, + num_layers=int(convnet_num_layers), + out_channels=out_channels, + use_batchnorm=conv2d_use_batchnorm, + ) + + elif self.prep_type == "conv1x1": + if temporal_downsample != 1: + raise ValueError("Conv1x1 does not downsample in time.") + self.convnet_1x1 = nn.Conv2d( + in_channels=in_channels, + out_channels=out_channels, + kernel_size=(1, 1), + # spatial_downsample is unconstrained for 1x1 convolutions. + stride=(spatial_downsample, spatial_downsample), + ) + + # Position embeddings + self.project_pos_dim = project_pos_dim + self.position_embeddings, self.positions_projection = build_position_encoding( + position_encoding_type=position_encoding_type, + out_channels=out_channels, + project_pos_dim=project_pos_dim, + **position_encoding_kwargs, + ) + + # Optional convolutional layer after patches. + self.conv_after_patches = ( + nn.Linear(conv_after_patching_in_channels, self.out_channels) if conv_after_patching else nn.Identity() + ) + + @property + def num_channels(self) -> int: + # Let's assume that the number of resolutions (in the context of image preprocessing) + # of the input data is 2 or 3 depending on whether we are processing image or video respectively. + # In this case, for convenience, we will declare is_temporal variable, + # which will show whether the data has a temporal dimension or not. + is_temporal = self.position_embeddings.num_dimensions > 2 + + # position embedding + if self.project_pos_dim > 0: + pos_dim = self.project_pos_dim + else: + pos_dim = self.position_embeddings.output_size() + if self.concat_or_add_pos == "add": + return pos_dim + + # inputs + if self.conv_after_patching or self.prep_type in ("conv1x1", "conv"): + inp_dim = self.out_channels + elif self.prep_type == "pixels": + inp_dim = self.in_channels + if not is_temporal: + inp_dim = math.ceil(inp_dim / self.spatial_downsample) + elif self.prep_type == "patches": + if self.conv_after_patching: + inp_dim = self.out_channels + else: + inp_dim = self.in_channels * self.spatial_downsample**2 + if is_temporal: + inp_dim *= self.temporal_downsample + + return inp_dim + pos_dim + + def _build_network_inputs( + self, inputs: torch.Tensor, network_input_is_1d: bool = True, interpolate_pos_encoding: bool = False + ): + """ + Construct the final input, including position encoding. + + This method expects the inputs to always have channels as last dimension. + + """ + batch_size = inputs.shape[0] + input_size = inputs.shape[1:3] + index_dims = inputs.shape[1:-1] + indices = np.prod(index_dims) + + # Flatten input features to a 1D index dimension if necessary. + if len(inputs.shape) > 3 and network_input_is_1d: + inputs = torch.reshape(inputs, [batch_size, indices, -1]) + + # Construct the position encoding. + if self.position_encoding_type == "trainable": + pos_enc = self.position_embeddings(batch_size, interpolate_pos_encoding, input_size) + elif self.position_encoding_type == "fourier": + pos_enc = self.position_embeddings(index_dims, batch_size, device=inputs.device, dtype=inputs.dtype) + + # Optionally project them to a target dimension. + pos_enc = self.positions_projection(pos_enc) + + if not network_input_is_1d: + # Reshape pos to match the input feature shape + # if the network takes non-1D inputs + sh = inputs.shape + pos_enc = torch.reshape(pos_enc, list(sh)[:-1] + [-1]) + if self.concat_or_add_pos == "concat": + inputs_with_pos = torch.cat([inputs, pos_enc], dim=-1) + elif self.concat_or_add_pos == "add": + inputs_with_pos = inputs + pos_enc + return inputs_with_pos, inputs + + def forward( + self, + inputs: torch.Tensor, + pos: torch.Tensor | None = None, + network_input_is_1d: bool = True, + interpolate_pos_encoding: bool = False, + ): + if self.prep_type == "conv": + # Convnet image featurization. + # Downsamples spatially by a factor of 4 + inputs = self.convnet(inputs) + + elif self.prep_type == "conv1x1": + # map inputs to self.out_channels + inputs = self.convnet_1x1(inputs) + + elif self.prep_type == "pixels": + # if requested, downsamples in the crudest way + if inputs.ndim == 4: + inputs = inputs[:: self.spatial_downsample, :: self.spatial_downsample] + elif inputs.ndim == 5: + inputs = inputs[ + :, :: self.temporal_downsample, :, :: self.spatial_downsample, :: self.spatial_downsample + ] + else: + raise ValueError("Unsupported data format for pixels.") + + elif self.prep_type == "patches": + # Space2depth featurization. + # Video: B x T x C x H x W + inputs = space_to_depth( + inputs, temporal_block_size=self.temporal_downsample, spatial_block_size=self.spatial_downsample + ) + + if inputs.ndim == 5 and inputs.shape[1] == 1: + # for flow + inputs = inputs.squeeze(dim=1) + + # Optionally apply conv layer. + inputs = self.conv_after_patches(inputs) + + if self.prep_type != "patches": + # move channels to last dimension, as the _build_network_inputs method below expects this + if inputs.ndim == 4: + inputs = inputs.permute(0, 2, 3, 1) + elif inputs.ndim == 5: + inputs = inputs.permute(0, 1, 3, 4, 2) + else: + raise ValueError("Unsupported data format for conv1x1.") + + inputs, inputs_without_pos = self._build_network_inputs(inputs, network_input_is_1d, interpolate_pos_encoding) + modality_sizes = None # Size for each modality, only needed for multimodal + + return inputs, modality_sizes, inputs_without_pos + + +class PerceiverOneHotPreprocessor(AbstractPreprocessor): + """ + One-hot preprocessor for Perceiver Encoder. Can be used to add a dummy index dimension to the input. + + Args: + config ([`PerceiverConfig`]): + Model configuration. + """ + + def __init__(self, config: PerceiverConfig) -> None: + super().__init__() + self.config: PerceiverConfig = config + + @property + def num_channels(self) -> int: + return self.config.num_labels + + def forward(self, inputs: torch.Tensor, pos: torch.Tensor | None = None, network_input_is_1d: bool = True): + # Add a dummy index dimension. + inputs = inputs[:, None, :] + + # No position encodings, so the 1st (input) and 3rd (inputs_without_pos) + # outputs are identical. + return inputs, None, inputs + + +class PerceiverAudioPreprocessor(AbstractPreprocessor): + """ + Audio preprocessing for Perceiver Encoder. + + Args: + config ([*PerceiverConfig*]): + Model configuration. + prep_type (`str`, *optional*, defaults to `"patches"`): + Preprocessor type to use. Only "patches" is supported. + samples_per_patch (`int`, *optional*, defaults to 96): + Number of samples per patch. + position_encoding_type (`str`, *optional*, defaults to `"fourier"`): + Type of position encoding to use. Can be "trainable" or "fourier". + concat_or_add_pos (`str`, *optional*, defaults to `"concat"`): + How to concatenate the position encoding to the input. Can be "concat" or "add". + out_channels (`int`, *optional*, defaults to 64): + Number of channels in the output. + project_pos_dim (`int`, *optional*, defaults to -1): + Dimension of the position encoding to project to. If -1, no projection is applied. + **position_encoding_kwargs (`Dict`, *optional*): + Keyword arguments for the position encoding. + """ + + def __init__( + self, + config, + prep_type: str = "patches", + samples_per_patch: int = 96, + position_encoding_type: str = "fourier", + concat_or_add_pos: str = "concat", + out_channels=64, + project_pos_dim=-1, + **position_encoding_kwargs, + ): + super().__init__() + self.config = config + + if prep_type != "patches": + raise ValueError(f"Prep_type {prep_type} is invalid, can only be 'patches'.") + + if concat_or_add_pos not in ["concat", "add"]: + raise ValueError(f"Concat_or_pos {concat_or_add_pos} is invalid, can only be 'concat' or 'add'.") + + self.samples_per_patch = samples_per_patch + self.position_encoding_type = position_encoding_type + self.concat_or_add_pos = concat_or_add_pos + self.project_pos_dim = project_pos_dim + + # Position embeddings + self.position_embeddings, self.positions_projection = build_position_encoding( + position_encoding_type=position_encoding_type, + out_channels=out_channels, + project_pos_dim=project_pos_dim, + **position_encoding_kwargs, + ) + + @property + def num_channels(self) -> int: + # position embedding + if self.project_pos_dim > 0: + pos_dim = self.project_pos_dim + else: + pos_dim = self.position_embeddings.output_size() + if self.concat_or_add_pos == "add": + return pos_dim + return self.samples_per_patch + pos_dim + + def _build_network_inputs(self, inputs): + """Construct the final input, including position encoding.""" + batch_size = inputs.shape[0] + index_dims = inputs.shape[1:-1] + + # Construct the position encoding. + if self.position_encoding_type == "trainable": + pos_enc = self.position_embeddings(batch_size) + elif self.position_encoding_type == "fourier": + pos_enc = self.position_embeddings(index_dims, batch_size, device=inputs.device, dtype=inputs.dtype) + + # Optionally project them to a target dimension. + pos_enc = self.positions_projection(pos_enc) + + if self.concat_or_add_pos == "concat": + inputs_with_pos = torch.cat([inputs, pos_enc], dim=-1) + elif self.concat_or_add_pos == "add": + inputs_with_pos = inputs + pos_enc + + return inputs_with_pos, inputs + + def forward( + self, + inputs: torch.Tensor, + pos: torch.Tensor | None = None, + network_input_is_1d: bool = True, + interpolate_pos_encoding: bool = False, + ): + inputs = torch.reshape(inputs, [inputs.shape[0], -1, self.samples_per_patch]) + + inputs, inputs_without_pos = self._build_network_inputs(inputs) + modality_sizes = None # Size for each modality, only needed for multimodal + + return inputs, modality_sizes, inputs_without_pos + + +class PerceiverMultimodalPreprocessor(AbstractPreprocessor): + """ + Multimodal preprocessing for Perceiver Encoder. + + Inputs for each modality are preprocessed, then padded with trainable position embeddings to have the same number + of channels. + + Args: + modalities (`Mapping[str, PreprocessorType]`): + Dict mapping modality name to preprocessor. + mask_probs (`dict[str, float]`): + Dict mapping modality name to masking probability of that modality. + min_padding_size (`int`, *optional*, defaults to 2): + The minimum padding size for all modalities. The final output will have num_channels equal to the maximum + channels across all modalities plus min_padding_size. + """ + + def __init__( + self, + modalities: Mapping[str, PreprocessorType], + mask_probs: Mapping[str, float] | None = None, + min_padding_size: int = 2, + ): + super().__init__() + self.modalities = nn.ModuleDict(modalities) + self.min_padding_size = min_padding_size + self.mask_probs = mask_probs if mask_probs is not None else {} + self.padding = nn.ParameterDict( + { + modality: nn.Parameter(torch.randn(1, self.num_channels - preprocessor.num_channels)) + for modality, preprocessor in modalities.items() + } + ) + self.mask = nn.ParameterDict( + {modality: nn.Parameter(torch.randn(1, self.num_channels)) for modality, _ in self.mask_probs.items()} + ) + + @property + def num_channels(self) -> int: + max_channel_size = max(processor.num_channels for _, processor in self.modalities.items()) + common_channel_size = max_channel_size + self.min_padding_size + return common_channel_size + + def forward( + self, + inputs: Mapping[str, torch.Tensor], + pos: torch.Tensor | None = None, + network_input_is_1d: bool = True, + interpolate_pos_encoding: bool = False, + ) -> PreprocessorOutputType: + padded = {} + modality_sizes = {} + inputs_without_pos = {} + for modality, preprocessor in self.modalities.items(): + # preprocess each modality using the respective preprocessor. + output, _, inputs_without_pos[modality] = preprocessor( + inputs[modality], pos=pos, network_input_is_1d=network_input_is_1d + ) + + # pad to the same common_channel_size. + batch_size, num_samples, num_channels = output.shape + pos_enc = self.padding[modality].expand(batch_size, -1, -1) + + padding = torch.broadcast_to( + pos_enc, + [batch_size, num_samples, self.num_channels - num_channels], + ) + output_padded = torch.cat([output, padding], dim=2) + + # mask if required + if modality in self.mask_probs: + mask_token = self.mask[modality].expand(batch_size, -1, -1) + mask_prob = self.mask_probs[modality] + mask = torch.bernoulli(torch.full([batch_size, num_samples], mask_prob)) + mask = torch.unsqueeze(mask, dim=2).to(mask_token.device) + output_padded = (1 - mask) * output_padded + mask * mask_token + + padded[modality] = output_padded + modality_sizes[modality] = output_padded.shape[1] + + # Apply a predictable ordering to the modalities + padded_ls = [padded[k] for k in sorted(padded.keys())] + + # Finally, concatenate along the time dimension + final_inputs = torch.cat(padded_ls, dim=1) + + return final_inputs, modality_sizes, inputs_without_pos + + +__all__ = [ + "PerceiverForImageClassificationConvProcessing", + "PerceiverForImageClassificationFourier", + "PerceiverForImageClassificationLearned", + "PerceiverForMaskedLM", + "PerceiverForMultimodalAutoencoding", + "PerceiverForOpticalFlow", + "PerceiverForSequenceClassification", + "PerceiverLayer", + "PerceiverModel", + "PerceiverPreTrainedModel", +] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/perceiver/tokenization_perceiver.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/perceiver/tokenization_perceiver.py new file mode 100644 index 0000000000000000000000000000000000000000..6abaf31aed11e601ef288a1d12d2bbedab36abb1 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/perceiver/tokenization_perceiver.py @@ -0,0 +1,197 @@ +# Copyright 2021 The HuggingFace Inc. team. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""Tokenization class for Perceiver.""" + +from ...tokenization_python import AddedToken, PreTrainedTokenizer +from ...utils import logging + + +logger = logging.get_logger(__name__) + + +class PerceiverTokenizer(PreTrainedTokenizer): + """ + Construct a Perceiver tokenizer. The Perceiver simply uses raw bytes utf-8 encoding. + + This tokenizer inherits from [`PreTrainedTokenizer`] which contains most of the main methods. Users should refer to + this superclass for more information regarding those methods. + + Args: + pad_token (`str`, *optional*, defaults to `"[PAD]"`): + The token used for padding, for example when batching sequences of different lengths. + bos_token (`str`, *optional*, defaults to `"[BOS]"`): + The BOS token (reserved in the vocab, but not actually used). + eos_token (`str`, *optional*, defaults to `"[EOS]"`): + The end of sequence token (reserved in the vocab, but not actually used). + + + + When building a sequence using special tokens, this is not the token that is used for the end of sequence. + The token used is the `sep_token`. + + + + mask_token (`str`, *optional*, defaults to `"[MASK]"`): + The MASK token, useful for masked language modeling. + cls_token (`str`, *optional*, defaults to `"[CLS]"`): + The CLS token (reserved in the vocab, but not actually used). + sep_token (`str`, *optional*, defaults to `"[SEP]"`): + The separator token, which is used when building a sequence from two sequences. + + """ + + model_input_names = ["input_ids", "attention_mask"] + + def __init__( + self, + pad_token="[PAD]", + bos_token="[BOS]", + eos_token="[EOS]", + mask_token="[MASK]", + cls_token="[CLS]", + sep_token="[SEP]", + model_max_length=2048, + **kwargs, + ) -> None: + pad_token = AddedToken(pad_token, lstrip=False, rstrip=False) if isinstance(pad_token, str) else pad_token + bos_token = AddedToken(bos_token, lstrip=False, rstrip=False) if isinstance(bos_token, str) else bos_token + eos_token = AddedToken(eos_token, lstrip=False, rstrip=False) if isinstance(eos_token, str) else eos_token + mask_token = AddedToken(mask_token, lstrip=False, rstrip=False) if isinstance(mask_token, str) else mask_token + cls_token = AddedToken(cls_token, lstrip=False, rstrip=False) if isinstance(cls_token, str) else cls_token + sep_token = AddedToken(sep_token, lstrip=False, rstrip=False) if isinstance(sep_token, str) else sep_token + + self._utf_vocab_size = 2**8 # utf is 8 bits + + # Since these tokens are not part of the vocabulary, we manually add them + self._added_tokens_decoder: dict[str, int] = { + 0: pad_token, + 1: bos_token, + 2: eos_token, + 3: mask_token, + 4: cls_token, + 5: sep_token, + } + self._num_special_tokens = len(self._added_tokens_decoder) + super().__init__( + pad_token=pad_token, + bos_token=bos_token, + eos_token=eos_token, + mask_token=mask_token, + cls_token=cls_token, + sep_token=sep_token, + model_max_length=model_max_length, + **kwargs, + ) + + def get_vocab(self) -> dict[str, int]: + vocab = {} + for i in range(self._utf_vocab_size): + token = chr(i) + vocab[token] = i + self._num_special_tokens + vocab.update(self.added_tokens_encoder) + return vocab + + @property + def vocab_size(self): + return self._utf_vocab_size + + def get_special_tokens_mask( + self, token_ids_0: list[int], token_ids_1: list[int] | None = None, already_has_special_tokens: bool = False + ) -> list[int]: + """ + Retrieve sequence ids from a token list that has no special tokens added. This method is called when adding + special tokens using the tokenizer `prepare_for_model` method. + + Args: + token_ids_0 (`list[int]`): + List of IDs. + token_ids_1 (`list[int]`, *optional*): + Optional second list of IDs for sequence pairs. + already_has_special_tokens (`bool`, *optional*, defaults to `False`): + Whether or not the token list is already formatted with special tokens for the model. + + Returns: + `list[int]`: A list of integers in the range [0, 1]: 1 for a special token, 0 for a sequence token. + """ + if already_has_special_tokens: + return super().get_special_tokens_mask( + token_ids_0=token_ids_0, token_ids_1=token_ids_1, already_has_special_tokens=True + ) + + # normal case: some special tokens + if token_ids_1 is None: + return [1] + [0] * len(token_ids_0) + [1] + return [1] + ([0] * len(token_ids_0)) + [1] + ([0] * len(token_ids_1)) + [1] + + def build_inputs_with_special_tokens( + self, token_ids_0: list[int], token_ids_1: list[int] | None = None + ) -> list[int]: + """ + Build model inputs from a sequence or a pair of sequence for sequence classification tasks. A sequence has the + following format: + + - single sequence: `[CLS] X [SEP]` + - pair of sequences: `[CLS] A [SEP] B [SEP]` + + Args: + token_ids_0 (`list[int]`): + List of IDs to which the special tokens will be added. + token_ids_1 (`list[int]`, *optional*): + Optional second list of IDs for sequence pairs. + + Returns: + `list[int]`: List of [input IDs](../glossary#input-ids) with the appropriate special tokens. + """ + if token_ids_1 is None: + return [self.cls_token_id] + token_ids_0 + [self.sep_token_id] + else: + return [self.cls_token_id] + token_ids_0 + [self.sep_token_id] + token_ids_1 + [self.sep_token_id] + + def _tokenize(self, text: str) -> list[str]: + """Take as input a string and return a list of strings (tokens) for words/sub-words""" + tokens = [chr(i) for i in text.encode("utf-8")] + return tokens + + def _convert_token_to_id(self, token): + """Converts a token (str) in an id using the vocab.""" + if len(token) != 1: + token_id = self.unk_token_id + else: + token_id = ord(token) + self._num_special_tokens + return token_id + + def _convert_id_to_token(self, index): + """Converts an index (integer) in a token (str) using the vocab.""" + token = chr(index - self._num_special_tokens) + return token + + # TODO @ArthurZ refactor this as well.... + def convert_tokens_to_string(self, tokens): + """Converts a sequence of tokens (string) in a single string.""" + bstring = b"" + for token in tokens: + if token in self.added_tokens_encoder: + tok_string = str(token).encode("utf-8") + else: + tok_string = bytes([ord(token)]) + bstring += tok_string + string = bstring.decode("utf-8", errors="replace") + return string + + # PerceiverTokenizer has no vocab file + def save_vocabulary(self, save_directory: str, filename_prefix: str | None = None) -> tuple[str]: + return () + + +__all__ = ["PerceiverTokenizer"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/perception_lm/__init__.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/perception_lm/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..81c3ba93bcf470394a99309dbf2f9869cd68d887 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/perception_lm/__init__.py @@ -0,0 +1,29 @@ +# Copyright 2025 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from typing import TYPE_CHECKING + +from ...utils import _LazyModule +from ...utils.import_utils import define_import_structure + + +if TYPE_CHECKING: + from .configuration_perception_lm import * + from .image_processing_perception_lm_fast import * + from .modeling_perception_lm import * + from .processing_perception_lm import * +else: + import sys + + _file = globals()["__file__"] + sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__) diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/perception_lm/configuration_perception_lm.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/perception_lm/configuration_perception_lm.py new file mode 100644 index 0000000000000000000000000000000000000000..10af8793aa15e1425c333864b7c59dbc95924625 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/perception_lm/configuration_perception_lm.py @@ -0,0 +1,87 @@ +# Copyright 2025 Meta Platforms, Inc. and the HuggingFace Inc. team. All rights reserved. +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""PerceptionLM model configuration""" + +from ...configuration_utils import PreTrainedConfig +from ...utils import logging +from ..auto import CONFIG_MAPPING, AutoConfig +from ..timm_wrapper.configuration_timm_wrapper import TimmWrapperConfig + + +logger = logging.get_logger(__name__) + + +class PerceptionLMConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`PerceptionLMForConditionalGeneration`]. It is used to instantiate an + PerceptionLM model according to the specified arguments, defining the model architecture. + + Example models: + - [facebook/Perception-LM-1B](https://huggingface.co/facebook/Perception-LM-1B). + - [facebook/Perception-LM-3B](https://huggingface.co/facebook/Perception-LM-3B). + - [facebook/Perception-LM-8B](https://huggingface.co/facebook/Perception-LM-8B). + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + vision_config (`Union[TimmWrapperConfig, dict]`, *optional*, defaults to `TimmWrapperConfig()`): + The config object or dictionary of the vision backbone. + text_config (`Union[PreTrainedConfig, dict]`, *optional*, defaults to `LlamaConfig()`): + The config object or dictionary of the text backbone. + vision_use_cls_token (`bool`, *optional*, defaults to `True`): + Whether CLS token is used in the vision backbone. If used, we remove CLS token embedding from vision output. + projector_pooling_ratio (`int`, *optional*, defaults to 1): + The pooling ratio used in the multimodal projector. + image_token_id (`int`, *optional*, defaults to 128002): + The image token index to encode the image prompt. + video_token_id (`int`, *optional*, defaults to 128003): + The video token index to encode the video prompt. + """ + + model_type = "perception_lm" + sub_configs = {"text_config": AutoConfig, "vision_config": TimmWrapperConfig} + + def __init__( + self, + vision_config=None, + text_config=None, + vision_use_cls_token=True, + projector_pooling_ratio=1, + image_token_id=128002, + video_token_id=128003, + **kwargs, + ): + self.image_token_id = image_token_id + self.video_token_id = video_token_id + if isinstance(vision_config, dict): + vision_config = TimmWrapperConfig(**vision_config) + elif isinstance(vision_config, TimmWrapperConfig): + pass + elif vision_config is None: + vision_config = TimmWrapperConfig() + self.vision_config = vision_config + self.vision_use_cls_token = vision_use_cls_token + + if isinstance(text_config, dict): + text_config["model_type"] = text_config.get("model_type", "llama") + text_config = CONFIG_MAPPING[text_config["model_type"]](**text_config) + elif text_config is None: + text_config = CONFIG_MAPPING["llama"]() + + self.text_config = text_config + self.projector_pooling_ratio = projector_pooling_ratio + super().__init__(**kwargs) + + +__all__ = ["PerceptionLMConfig"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/perception_lm/image_processing_perception_lm_fast.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/perception_lm/image_processing_perception_lm_fast.py new file mode 100644 index 0000000000000000000000000000000000000000..440ff0487d71c64946a5ffe3cc22b698f019d5e3 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/perception_lm/image_processing_perception_lm_fast.py @@ -0,0 +1,312 @@ +# Copyright 2025 Meta Platforms, Inc. and the HuggingFace Inc. team. All rights reserved. +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""Fast Image processor class for PerceptionLM.""" + +import math +from functools import reduce + +import numpy as np +import torch +from torchvision.transforms import functional as F + +from ...image_processing_utils import ( + BatchFeature, +) +from ...image_processing_utils_fast import ( + BaseImageProcessorFast, + get_image_size, + group_images_by_shape, + reorder_images, +) +from ...image_utils import ( + IMAGENET_STANDARD_MEAN, + IMAGENET_STANDARD_STD, + ChannelDimension, + PILImageResampling, +) +from ...processing_utils import ImagesKwargs, Unpack +from ...utils import ( + TensorType, + auto_docstring, +) + + +class PerceptionLMImageProcessorKwargs(ImagesKwargs, total=False): + r""" + vision_input_type (`str`, *optional*, defaults to `"thumb+tile"`): + Vision processing strategy. `"thumb+tile"` uses both thumbnails and multiple tiles for + multi-scale processing, otherwise uses single tile for lower memory usage. + tile_size (`int`, *optional*, defaults to `448`): + Height and width dimension (in pixels) of each tile used for image processing. + max_num_tiles (`int`, *optional*, defaults to `36`): + Maximum number of tiles an image can be split into based on its aspect ratio. + """ + + vision_input_type: str | None + tile_size: int + max_num_tiles: int + + +@auto_docstring +class PerceptionLMImageProcessorFast(BaseImageProcessorFast): + resample = PILImageResampling.BICUBIC + image_mean = IMAGENET_STANDARD_MEAN + image_std = IMAGENET_STANDARD_STD + do_resize = True + do_center_crop = False + do_rescale = True + do_normalize = True + do_convert_rgb = True + vision_input_type = "thumb+tile" + tile_size = 448 + max_num_tiles = 36 + size = {"width": 448, "height": 448} # for backward compatibility in tests + valid_kwargs = PerceptionLMImageProcessorKwargs + + def __init__(self, **kwargs: Unpack[PerceptionLMImageProcessorKwargs]) -> None: + super().__init__(**kwargs) + + @auto_docstring + def preprocess(self, images, **kwargs: Unpack[PerceptionLMImageProcessorKwargs]) -> BatchFeature: + return super().preprocess(images, **kwargs) + + @staticmethod + def _factors(n: int): + """Return all factors of a number.""" + return set( + reduce( + list.__add__, + ([i, n // i] for i in range(1, int(n**0.5) + 1) if n % i == 0), + ) + ) + + def _find_supported_aspect_ratios(self): + """ + This function computes all the allowed aspect ratios for a fixed + number of input chunks. The order of returned items matters for the result of `_fit_image_to_canvas` function. + If tie exists in `_fit_image_to_canvas`, the latter in `_find_supported_aspect_ratios` wins. + + For example, with `num_tiles=5`, it will return: + { + 0.2: [(1, 5)], + 5.0: [(5, 1)], + 0.25: [(1, 4)], + 1.0: [(2, 2), (1, 1)], + 4.0: [(4, 1)], + 0.3333333333333333: [(1, 3)], + 3.0: [(3, 1)], + 0.5: [(1, 2)], + 2.0: [(2, 1)] + } + """ + asp_dict = {} + for chunk_size in range(self.max_num_tiles, 0, -1): + _factors = sorted(self._factors(chunk_size)) + _asp_ratios = [(x, chunk_size // x) for x in _factors] + for ratio in _asp_ratios: + k = ratio[0] / ratio[1] + if k not in asp_dict: + asp_dict[k] = [ratio] + else: + asp_dict[k].append(ratio) + return asp_dict + + def _get_image_height_width( + self, image_width: int, image_height: int, target_width: int, target_height: int + ) -> tuple[int, int]: + """ + Given image width, height and target width, height for the canvas, return the dimensions of how the image would be resized + with aspect ratio preservation. + """ + scale = image_width / image_height + + if scale > 1.0: + # Width is larger than height + + # Rescaling factor is the minimum of the two scaling factors. Else one side would be outside of the canvas. + rescaling_factor = min(target_width / image_width, target_height / image_height) + + # Set new width to target width and height to the rescaled height. + new_w = rescaling_factor * image_width + new_h = math.floor(new_w / scale) + + else: + # Height is larger than width + + # Rescaling factor is the minimum of the two scaling factors. Else one side would be outside of the canvas. + rescaling_factor = min(target_width / image_width, target_height / image_height) + + # Set new height to target height and width to the rescaled width. + new_h = rescaling_factor * image_height + new_w = math.floor(new_h * scale) + + return new_w, new_h + + def _fit_image_to_canvas(self, img_width: int, img_height: int, tile_size: int): + """ + Given an image width, height and target number of chunks this function will see if the image + can be fit into any of the canvases that can be build from arranging the tiles in a grid. + If the image can be fit onto several canvases, it will return the canvas where the shorter edge + of the image will be largest. + """ + # Initialize the optimal canvas to None. If no canvas is found where image fits, function returns None. + optimal_canvas = None + optimal_image_width_height = None + + scale = img_width / img_height + + # Gather all potential supported image resolutions and iterate through them to find best match + potential_arrangements = [ + item for sublist in self._find_supported_aspect_ratios().values() for item in sublist + ] + for n_w, n_h in potential_arrangements: + # Compute the canvas size + canvas_width, canvas_height = n_w * tile_size, n_h * tile_size + + # Check if image can fit into the canvas without downsampling + if canvas_width >= img_width and canvas_height >= img_height: + # If we did not find a good canvas yet, we will use the current one + if optimal_canvas is None: + # Set optimal canvas and determine the actual image height and width in the canvas with aspect ratio preserving resampling + optimal_canvas = (n_w, n_h) + optimal_image_width_height = self._get_image_height_width( + image_width=img_width, + image_height=img_height, + target_width=n_w * tile_size, + target_height=n_h * tile_size, + ) + else: + # If we already found an optimal canvas before, we will check if the shorter edge of the image will be larger than the current optimal canvas. + # This means we can potentially upsample the image resolution which is beneficial to performance. + image_width_height = self._get_image_height_width( + image_width=img_width, + image_height=img_height, + target_width=n_w * tile_size, + target_height=n_h * tile_size, + ) + # Llama3V dynamic tiling. Prioritize biggest canvas. + if (scale < 1.0 and (image_width_height[0] >= optimal_image_width_height[0])) or ( + scale >= 1.0 and (image_width_height[1] >= optimal_image_width_height[1]) + ): + optimal_canvas = (n_w, n_h) + optimal_image_width_height = image_width_height + return optimal_canvas + + def _find_closest_aspect_ratio(self, img_width: int, img_height: int, tile_size: int) -> tuple: + """ + Given an image width, height and target number of chunks + this function will find the closest supported aspect ratio. + """ + target_aspect_ratio = img_width / img_height + asp_dict = self._find_supported_aspect_ratios() + closest_aspect_ratio = None + if target_aspect_ratio >= 1: + closest_aspect_ratio = min( + [k for k in asp_dict if k <= target_aspect_ratio], + key=lambda x: abs(x - target_aspect_ratio), + ) + tiles_given_aspect_ratio = asp_dict[closest_aspect_ratio] + # select largest width + return max(tiles_given_aspect_ratio, key=lambda x: x[0]) + else: + closest_aspect_ratio = min( + [k for k in asp_dict if k > target_aspect_ratio], + key=lambda x: abs(1 / x - 1 / target_aspect_ratio), + ) + tiles_given_aspect_ratio = asp_dict[closest_aspect_ratio] + # select largest height + return max(tiles_given_aspect_ratio, key=lambda x: x[1]) + + def _split(self, image: torch.Tensor, ncw: int, nch: int) -> torch.Tensor: + # Split image into number of required tiles (width x height) + batch_size, num_channels, height, width = image.size() + image = image.view(batch_size, num_channels, nch, height // nch, ncw, width // ncw) + # Permute dimensions to reorder the axes + image = image.permute(0, 2, 4, 1, 3, 5).contiguous() + # Reshape into the desired output shape (batch_size * 4, num_channels, width/2, height/2) + image = image.view(batch_size, ncw * nch, num_channels, height // nch, width // ncw) + return image + + def resize( + self, + image: np.ndarray, + tile_size: int, + max_num_tiles: int, + resample: PILImageResampling = PILImageResampling.BICUBIC, + input_data_format: str | ChannelDimension | None = None, + ): + height, width = get_image_size(image, channel_dim=input_data_format) + if max_num_tiles > 1: + aspect_ratio = self._fit_image_to_canvas(img_width=width, img_height=height, tile_size=tile_size) + if aspect_ratio is None: + # If we did not find a canvas, we have to find the closest aspect ratio and downsample the image + aspect_ratio = self._find_closest_aspect_ratio(img_width=width, img_height=height, tile_size=tile_size) + else: + aspect_ratio = (1, 1) + new_width, new_height = aspect_ratio[0] * tile_size, aspect_ratio[1] * tile_size + image = F.resize(image, (new_height, new_width), interpolation=resample) + return image, aspect_ratio + + def _preprocess( + self, + images: list["torch.Tensor"], + do_resize: bool, + do_rescale: bool | None, + rescale_factor: int | float | None, + do_normalize: bool | None, + image_mean: float | list[float] | None, + image_std: float | list[float] | None, + vision_input_type: str, + tile_size: int, + max_num_tiles: int, + return_tensors: str | TensorType | None, + disable_grouping: bool, + **kwargs: Unpack[PerceptionLMImageProcessorKwargs], + ) -> BatchFeature: + # Group images by size for batched transformation + grouped_images, grouped_images_index = group_images_by_shape(images, disable_grouping=disable_grouping) + resized_images_grouped = {} + for shape, stacked_images in grouped_images.items(): + if do_resize: + if vision_input_type == "thumb+tile": + thumbnails, _ = self.resize(stacked_images, tile_size, max_num_tiles=1) + images_for_tiling, (tiles_w, tiles_h) = self.resize( + stacked_images, tile_size, max_num_tiles=max_num_tiles + ) + image_tiles = self._split(images_for_tiling, tiles_w, tiles_h) + stacked_images = torch.cat([thumbnails.unsqueeze(1), image_tiles], dim=1) + else: # vanilla single tile for low memory devices + stacked_images, _ = self.resize(stacked_images, tile_size, max_num_tiles=1) + + resized_images_grouped[shape] = stacked_images + resized_images = reorder_images(resized_images_grouped, grouped_images_index) + + grouped_images, grouped_images_index = group_images_by_shape(resized_images, disable_grouping=disable_grouping) + processed_images_grouped = {} + for shape, stacked_images in grouped_images.items(): + # Fused rescale and normalize + stacked_images = self.rescale_and_normalize( + stacked_images, + do_rescale, + rescale_factor, + do_normalize, + image_mean, + image_std, + ) + processed_images_grouped[shape] = stacked_images + processed_images = reorder_images(processed_images_grouped, grouped_images_index) + processed_images = [p[None] if p.ndim == 3 else p for p in processed_images] # add tiles dimension if needed + return BatchFeature(data={"pixel_values": processed_images}, tensor_type=return_tensors) + + +__all__ = ["PerceptionLMImageProcessorFast"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/perception_lm/modeling_perception_lm.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/perception_lm/modeling_perception_lm.py new file mode 100644 index 0000000000000000000000000000000000000000..7957d3bbd143777c378bb87633fef8511775354a --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/perception_lm/modeling_perception_lm.py @@ -0,0 +1,477 @@ +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# This file was automatically generated from src/transformers/models/perception_lm/modular_perception_lm.py. +# Do NOT edit this file manually as any edits will be overwritten by the generation of +# the file from the modular. If any change should be done, please apply the change to the +# modular_perception_lm.py file directly. One of our CI enforces this. +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# Copyright 2025 Meta Platforms, Inc. and the HuggingFace Inc. team. All rights reserved. +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import math +from dataclasses import dataclass + +import torch +import torch.nn.functional as F +from torch import nn + +from ...cache_utils import Cache +from ...generation import GenerationMixin +from ...modeling_outputs import BaseModelOutputWithPast, BaseModelOutputWithPooling, ModelOutput +from ...modeling_utils import PreTrainedModel +from ...processing_utils import Unpack +from ...utils import TransformersKwargs, auto_docstring, can_return_tuple, torch_compilable_check +from ..auto import AutoModel +from .configuration_perception_lm import PerceptionLMConfig + + +class PerceptionLMAdaptiveAvgPooling(nn.Module): + def __init__(self, pooling_ratio=2): + super().__init__() + self.pooling_ratio = pooling_ratio + + def forward(self, hidden_states): + b, num_tokens, c = hidden_states.shape + h = int(math.sqrt(num_tokens)) + if h * h != num_tokens: + raise ValueError(f"num_tokens {num_tokens} is expected to be a square number") + + shape = (h // self.pooling_ratio, h // self.pooling_ratio) + hidden_states = hidden_states.permute(0, 2, 1).reshape(b, -1, h, h) + hidden_states = F.adaptive_avg_pool2d(hidden_states, shape) + hidden_states = hidden_states.flatten(2).transpose(1, 2) + + return hidden_states + + +class PerceptionLMMultiModalProjector(nn.Module): + def __init__(self, config: PerceptionLMConfig): + super().__init__() + input_size = config.vision_config.model_args["embed_dim"] + output_size = config.text_config.hidden_size + self.linear_1 = nn.Linear( + in_features=input_size, + out_features=output_size, + bias=True, + ) + self.gelu = nn.GELU() + self.linear_2 = nn.Linear( + in_features=output_size, + out_features=output_size, + bias=True, + ) + self.pooling = ( + PerceptionLMAdaptiveAvgPooling(config.projector_pooling_ratio) + if config.projector_pooling_ratio > 1 + else nn.Identity() + ) + + def forward(self, features): + features = features.permute(1, 0, 2) # NLD -> LND + features = self.linear_1(features) + features = self.gelu(features) + features = self.linear_2(features) + features = features.permute(1, 0, 2) # LND -> NLD + features = self.pooling(features) + return features + + +@auto_docstring +class PerceptionLMPreTrainedModel(PreTrainedModel): + config: PerceptionLMConfig + base_model_prefix = "model" + input_modalities = ("image", "text") + supports_gradient_checkpointing = True + _skip_keys_device_placement = "past_key_values" + + _supports_flash_attn = True + _supports_sdpa = True + + _can_compile_fullgraph = True + _supports_flex_attn = True + _supports_attention_backend = True + + +@dataclass +@auto_docstring( + custom_intro=""" + Base class for PerceptionLM outputs, with hidden states and attentions. + """ +) +class PerceptionLMModelOutputWithPast(BaseModelOutputWithPast): + r""" + past_key_values (`Cache`, *optional*, returned when `use_cache=True` is passed or when `config.use_cache=True`): + It is a [`~cache_utils.Cache`] instance. For more details, see our [kv cache guide](https://huggingface.co/docs/transformers/en/kv_cache). + + Contains pre-computed hidden-states (key and values in the self-attention blocks) that can be used (see + `past_key_values` input) to speed up sequential decoding. + image_hidden_states (`torch.FloatTensor`, *optional*): + A `torch.FloatTensor` of size `(batch_size, num_images, sequence_length, hidden_size)`. + Image hidden_states of the model produced by the vision encoder and after projecting the last hidden state. + video_hidden_states (`torch.FloatTensor`, *optional*): + A `torch.FloatTensor` of size `(batch_size, num_videos, sequence_length, hidden_size)`. + Video hidden_states of the model produced by the vision encoder and after projecting the last hidden state. + """ + + image_hidden_states: torch.FloatTensor | None = None + + video_hidden_states: torch.FloatTensor | None = None + + +@dataclass +@auto_docstring( + custom_intro=""" + Base class for PerceptionLM causal language model (or autoregressive) outputs. + """ +) +class PerceptionLMCausalLMOutputWithPast(ModelOutput): + r""" + loss (`torch.FloatTensor` of shape `(1,)`, *optional*, returned when `labels` is provided): + Language modeling loss (for next-token prediction). + logits (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.vocab_size)`): + Prediction scores of the language modeling head (scores for each vocabulary token before SoftMax). + past_key_values (`Cache`, *optional*, returned when `use_cache=True` is passed or when `config.use_cache=True`): + It is a [`~cache_utils.Cache`] instance. For more details, see our [kv cache guide](https://huggingface.co/docs/transformers/en/kv_cache). + + Contains pre-computed hidden-states (key and values in the self-attention blocks) that can be used (see + `past_key_values` input) to speed up sequential decoding. + image_hidden_states (`torch.FloatTensor`, *optional*): + A `torch.FloatTensor` of size `(batch_size, num_images, sequence_length, hidden_size)`. + Image hidden_states of the model produced by the vision encoder and after projecting the last hidden state. + video_hidden_states (`torch.FloatTensor`, *optional*): + A `torch.FloatTensor` of size `(batch_size, num_videos, sequence_length, hidden_size)`. + Video hidden_states of the model produced by the vision encoder and after projecting the last hidden state. + """ + + loss: torch.FloatTensor | None = None + logits: torch.FloatTensor | None = None + past_key_values: Cache | None = None + hidden_states: tuple[torch.FloatTensor] | None = None + attentions: tuple[torch.FloatTensor] | None = None + image_hidden_states: torch.FloatTensor | None = None + + video_hidden_states: torch.FloatTensor | None = None + + +@auto_docstring +class PerceptionLMModel(PerceptionLMPreTrainedModel): + _checkpoint_conversion_mapping = {} + + def __init__(self, config: PerceptionLMConfig): + super().__init__(config) + self.vision_tower = AutoModel.from_config(config.vision_config) + self.multi_modal_projector = PerceptionLMMultiModalProjector(config) + self.language_model = AutoModel.from_config(config.text_config) + self.post_init() + + def get_input_embeddings(self): + return self.language_model.get_input_embeddings() + + def set_input_embeddings(self, value): + self.language_model.set_input_embeddings(value) + + @can_return_tuple + @auto_docstring( + custom_intro="Obtains image last hidden states from the vision tower and apply multimodal projection." + ) + def get_image_features( + self, + pixel_values: torch.FloatTensor, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple | BaseModelOutputWithPooling: + image_outputs = self.vision_tower(pixel_values.flatten(0, 1), return_dict=True, **kwargs) + last_hidden_state = image_outputs.last_hidden_state + if self.config.vision_use_cls_token: + last_hidden_state = last_hidden_state[:, 1:, :] + image_features = self.multi_modal_projector(last_hidden_state) + image_outputs.pooler_output = image_features + + return image_outputs + + def get_placeholder_mask( + self, + input_ids: torch.LongTensor, + inputs_embeds: torch.FloatTensor, + image_features: torch.FloatTensor | None = None, + video_features: torch.FloatTensor | None = None, + ): + """ + Obtains multimodal placeholder mask from `input_ids` or `inputs_embeds`, and checks that the placeholder token count is + equal to the length of multimodal features. If the lengths are different, an error is raised. + """ + if input_ids is None: + special_image_mask = inputs_embeds == self.get_input_embeddings()( + torch.tensor(self.config.image_token_id, dtype=torch.long, device=inputs_embeds.device) + ) + special_image_mask = special_image_mask.all(-1) + special_video_mask = inputs_embeds == self.get_input_embeddings()( + torch.tensor(self.config.video_token_id, dtype=torch.long, device=inputs_embeds.device) + ) + special_video_mask = special_video_mask.all(-1) + else: + special_image_mask = input_ids == self.config.image_token_id + special_video_mask = input_ids == self.config.video_token_id + + n_image_tokens = special_image_mask.sum() + special_image_mask = special_image_mask.unsqueeze(-1).expand_as(inputs_embeds).to(inputs_embeds.device) + if image_features is not None: + torch_compilable_check( + inputs_embeds[special_image_mask].numel() == image_features.numel(), + f"Image features and image tokens do not match, tokens: {n_image_tokens}, features: {image_features.size()[:-1].numel()}", + ) + + n_video_tokens = special_video_mask.sum() + special_video_mask = special_video_mask.unsqueeze(-1).expand_as(inputs_embeds).to(inputs_embeds.device) + if video_features is not None: + torch_compilable_check( + inputs_embeds[special_video_mask].numel() == video_features.numel(), + f"Video features and video tokens do not match, tokens: {n_video_tokens}, features: {video_features.size()[:-1].numel()}", + ) + return special_image_mask, special_video_mask + + @can_return_tuple + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + pixel_values: torch.FloatTensor | None = None, + pixel_values_videos: torch.FloatTensor | None = None, + attention_mask: torch.Tensor | None = None, + position_ids: torch.LongTensor | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.FloatTensor | None = None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + cache_position: torch.LongTensor | None = None, + logits_to_keep: int | torch.Tensor = 0, + **lm_kwargs, + ) -> tuple | PerceptionLMModelOutputWithPast: + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + if (input_ids is None) ^ (inputs_embeds is not None): + raise ValueError("You must specify exactly one of input_ids or inputs_embeds") + if (pixel_values is not None or pixel_values_videos is not None) and inputs_embeds is not None: + raise ValueError( + "You cannot specify both (pixel_values or pixel_values_videos) and inputs_embeds at the same time, and must specify either one" + ) + + if inputs_embeds is None: + inputs_embeds = self.get_input_embeddings()(input_ids) + + image_features = None + if pixel_values is not None: + image_features = self.get_image_features(pixel_values=pixel_values, return_dict=True).pooler_output + image_features = image_features.to(inputs_embeds.device, dtype=inputs_embeds.dtype) + special_image_mask, _ = self.get_placeholder_mask( + input_ids, inputs_embeds=inputs_embeds, image_features=image_features + ) + inputs_embeds = inputs_embeds.masked_scatter(special_image_mask, image_features) + + video_features = None + if pixel_values_videos is not None: + video_features = self.get_image_features(pixel_values=pixel_values_videos, return_dict=True).pooler_output + video_features = video_features.to(inputs_embeds.device, dtype=inputs_embeds.dtype) + _, special_video_mask = self.get_placeholder_mask( + input_ids, inputs_embeds=inputs_embeds, video_features=video_features + ) + inputs_embeds = inputs_embeds.masked_scatter(special_video_mask, video_features) + + outputs = self.language_model( + attention_mask=attention_mask, + position_ids=position_ids, + past_key_values=past_key_values, + inputs_embeds=inputs_embeds, + use_cache=use_cache, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=True, + cache_position=cache_position, + logits_to_keep=logits_to_keep, + **lm_kwargs, + ) + return PerceptionLMModelOutputWithPast( + last_hidden_state=outputs.last_hidden_state, + hidden_states=outputs.hidden_states, + past_key_values=outputs.past_key_values, + attentions=outputs.attentions, + image_hidden_states=image_features if pixel_values is not None else None, + video_hidden_states=(video_features if pixel_values_videos is not None else None), + ) + + +@auto_docstring +class PerceptionLMForConditionalGeneration(PerceptionLMPreTrainedModel, GenerationMixin): + _checkpoint_conversion_mapping = {} + _tied_weights_keys = {"lm_head.weight": "model.language_model.embed_tokens.weight"} + + def __init__(self, config: PerceptionLMConfig): + super().__init__(config) + self.model = PerceptionLMModel(config) + self.lm_head = nn.Linear(config.text_config.hidden_size, config.text_config.vocab_size, bias=False) + self.post_init() + + def get_input_embeddings(self): + return self.model.get_input_embeddings() + + def set_input_embeddings(self, value): + self.model.set_input_embeddings(value) + + def get_output_embeddings(self) -> nn.Module: + return self.lm_head + + @can_return_tuple + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + pixel_values: torch.FloatTensor | None = None, + pixel_values_videos: torch.FloatTensor | None = None, + attention_mask: torch.Tensor | None = None, + position_ids: torch.LongTensor | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.FloatTensor | None = None, + labels: torch.LongTensor | None = None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + cache_position: torch.LongTensor | None = None, + logits_to_keep: int | torch.Tensor = 0, + **lm_kwargs, + ) -> tuple | PerceptionLMCausalLMOutputWithPast: + r""" + labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Labels for computing the masked language modeling loss. Indices should either be in `[0, ..., + config.vocab_size]` or -100 (see `input_ids` docstring). Tokens with indices set to `-100` are ignored + (masked), the loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]`. + + Example: + + ```python + from transformers import AutoProcessor, AutoModelForImageTextToText + from huggingface_hub import hf_hub_download + + MODEL_PATH = "facebook/Perception-LM-1B" + processor = AutoProcessor.from_pretrained(MODEL_PATH, use_fast=True) + model = AutoModelForImageTextToText.from_pretrained(MODEL_PATH).to("cuda") + test_image_file = hf_hub_download( + repo_id="shumingh/perception_lm_test_images", + filename="14496_0.PNG", + repo_type="dataset", + ) + conversation = [ + { + "role": "user", + "content": [ + { + "type": "image", + "url": test_image_file, + }, + {"type": "text", "text": "Describe the bar plot in the image."}, + ], + } + ] + + inputs = processor.apply_chat_template( + [conversation], + add_generation_prompt=True, + tokenize=True, + return_dict=True, + return_tensors="pt", + ) + inputs = inputs.to(model.device) + generate_ids = model.generate(**inputs, max_new_tokens=256) + input_length = inputs["input_ids"].shape[1] + generate_ids_without_inputs = generate_ids[:, input_length:] + + for output in processor.batch_decode(generate_ids_without_inputs, skip_special_tokens=True): + print(output) + ```""" + outputs = self.model( + input_ids=input_ids, + pixel_values=pixel_values, + pixel_values_videos=pixel_values_videos, + attention_mask=attention_mask, + position_ids=position_ids, + past_key_values=past_key_values, + inputs_embeds=inputs_embeds, + use_cache=use_cache, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + cache_position=cache_position, + logits_to_keep=logits_to_keep, + **lm_kwargs, + ) + + hidden_states = outputs[0] + # Only compute necessary logits, and do not upcast them to float if we are not computing the loss + slice_indices = slice(-logits_to_keep, None) if isinstance(logits_to_keep, int) else logits_to_keep + logits = self.lm_head(hidden_states[:, slice_indices, :]) + + loss = None + if labels is not None: + loss = self.loss_function( + logits=logits, + labels=labels, + vocab_size=self.config.text_config.vocab_size, + **lm_kwargs, + ) + + return PerceptionLMCausalLMOutputWithPast( + loss=loss, + logits=logits, + past_key_values=outputs.past_key_values, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + image_hidden_states=outputs.image_hidden_states, + video_hidden_states=outputs.video_hidden_states, + ) + + def prepare_inputs_for_generation( + self, + input_ids, + past_key_values=None, + inputs_embeds=None, + pixel_values=None, + pixel_values_videos=None, + attention_mask=None, + cache_position=None, + logits_to_keep=None, + is_first_iteration=False, + **kwargs, + ): + # Overwritten -- in specific circumstances we don't want to forward image inputs to the model + + model_inputs = super().prepare_inputs_for_generation( + input_ids, + past_key_values=past_key_values, + inputs_embeds=inputs_embeds, + attention_mask=attention_mask, + cache_position=cache_position, + logits_to_keep=logits_to_keep, + is_first_iteration=is_first_iteration, + **kwargs, + ) + + if is_first_iteration or not kwargs.get("use_cache", True): + # Pixel values are used only in the first iteration if available + # In subsequent iterations, they are already merged with text and cached + # NOTE: first iteration doesn't have to be prefill, it can be the first + # iteration with a question and cached system prompt (continue generate from cache) + model_inputs["pixel_values"] = pixel_values + model_inputs["pixel_values_videos"] = pixel_values_videos + return model_inputs + + +__all__ = ["PerceptionLMForConditionalGeneration", "PerceptionLMPreTrainedModel", "PerceptionLMModel"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/perception_lm/modular_perception_lm.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/perception_lm/modular_perception_lm.py new file mode 100644 index 0000000000000000000000000000000000000000..e2d2df573720497184b1b85c11f8bbf88768f37a --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/perception_lm/modular_perception_lm.py @@ -0,0 +1,436 @@ +# Copyright 2025 Meta Platforms, Inc. and the HuggingFace Inc. team. All rights reserved. +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""PyTorch PerceptionLM model.""" + +import math + +import torch +import torch.nn.functional as F +from torch import nn + +from ...cache_utils import Cache +from ...modeling_outputs import BaseModelOutputWithPooling +from ...processing_utils import Unpack +from ...utils import ( + TransformersKwargs, + auto_docstring, + can_return_tuple, + logging, + torch_compilable_check, +) +from ..auto import AutoModel +from ..llava.modeling_llava import ( + LlavaCausalLMOutputWithPast, + LlavaForConditionalGeneration, + LlavaModel, + LlavaModelOutputWithPast, + LlavaPreTrainedModel, +) +from .configuration_perception_lm import PerceptionLMConfig + + +logger = logging.get_logger(__name__) + + +class PerceptionLMAdaptiveAvgPooling(nn.Module): + def __init__(self, pooling_ratio=2): + super().__init__() + self.pooling_ratio = pooling_ratio + + def forward(self, hidden_states): + b, num_tokens, c = hidden_states.shape + h = int(math.sqrt(num_tokens)) + if h * h != num_tokens: + raise ValueError(f"num_tokens {num_tokens} is expected to be a square number") + + shape = (h // self.pooling_ratio, h // self.pooling_ratio) + hidden_states = hidden_states.permute(0, 2, 1).reshape(b, -1, h, h) + hidden_states = F.adaptive_avg_pool2d(hidden_states, shape) + hidden_states = hidden_states.flatten(2).transpose(1, 2) + + return hidden_states + + +class PerceptionLMMultiModalProjector(nn.Module): + def __init__(self, config: PerceptionLMConfig): + super().__init__() + input_size = config.vision_config.model_args["embed_dim"] + output_size = config.text_config.hidden_size + self.linear_1 = nn.Linear( + in_features=input_size, + out_features=output_size, + bias=True, + ) + self.gelu = nn.GELU() + self.linear_2 = nn.Linear( + in_features=output_size, + out_features=output_size, + bias=True, + ) + self.pooling = ( + PerceptionLMAdaptiveAvgPooling(config.projector_pooling_ratio) + if config.projector_pooling_ratio > 1 + else nn.Identity() + ) + + def forward(self, features): + features = features.permute(1, 0, 2) # NLD -> LND + features = self.linear_1(features) + features = self.gelu(features) + features = self.linear_2(features) + features = features.permute(1, 0, 2) # LND -> NLD + features = self.pooling(features) + return features + + +class PerceptionLMPreTrainedModel(LlavaPreTrainedModel): + base_model_prefix = "model" + + +class PerceptionLMModelOutputWithPast(LlavaModelOutputWithPast): + r""" + past_key_values (`Cache`, *optional*, returned when `use_cache=True` is passed or when `config.use_cache=True`): + It is a [`~cache_utils.Cache`] instance. For more details, see our [kv cache guide](https://huggingface.co/docs/transformers/en/kv_cache). + + Contains pre-computed hidden-states (key and values in the self-attention blocks) that can be used (see + `past_key_values` input) to speed up sequential decoding. + image_hidden_states (`torch.FloatTensor`, *optional*): + A `torch.FloatTensor` of size `(batch_size, num_images, sequence_length, hidden_size)`. + Image hidden_states of the model produced by the vision encoder and after projecting the last hidden state. + video_hidden_states (`torch.FloatTensor`, *optional*): + A `torch.FloatTensor` of size `(batch_size, num_videos, sequence_length, hidden_size)`. + Video hidden_states of the model produced by the vision encoder and after projecting the last hidden state. + """ + + video_hidden_states: torch.FloatTensor | None = None + + +class PerceptionLMCausalLMOutputWithPast(LlavaCausalLMOutputWithPast): + r""" + loss (`torch.FloatTensor` of shape `(1,)`, *optional*, returned when `labels` is provided): + Language modeling loss (for next-token prediction). + logits (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.vocab_size)`): + Prediction scores of the language modeling head (scores for each vocabulary token before SoftMax). + past_key_values (`Cache`, *optional*, returned when `use_cache=True` is passed or when `config.use_cache=True`): + It is a [`~cache_utils.Cache`] instance. For more details, see our [kv cache guide](https://huggingface.co/docs/transformers/en/kv_cache). + + Contains pre-computed hidden-states (key and values in the self-attention blocks) that can be used (see + `past_key_values` input) to speed up sequential decoding. + image_hidden_states (`torch.FloatTensor`, *optional*): + A `torch.FloatTensor` of size `(batch_size, num_images, sequence_length, hidden_size)`. + Image hidden_states of the model produced by the vision encoder and after projecting the last hidden state. + video_hidden_states (`torch.FloatTensor`, *optional*): + A `torch.FloatTensor` of size `(batch_size, num_videos, sequence_length, hidden_size)`. + Video hidden_states of the model produced by the vision encoder and after projecting the last hidden state. + """ + + video_hidden_states: torch.FloatTensor | None = None + + +@auto_docstring +class PerceptionLMModel(LlavaModel): + _checkpoint_conversion_mapping = {} + + def __init__(self, config: PerceptionLMConfig): + super().__init__(config) + self.vision_tower = AutoModel.from_config(config.vision_config) + self.multi_modal_projector = PerceptionLMMultiModalProjector(config) + self.language_model = AutoModel.from_config(config.text_config) + + @can_return_tuple + @auto_docstring( + custom_intro="Obtains image last hidden states from the vision tower and apply multimodal projection." + ) + def get_image_features( + self, + pixel_values: torch.FloatTensor, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple | BaseModelOutputWithPooling: + image_outputs = self.vision_tower(pixel_values.flatten(0, 1), return_dict=True, **kwargs) + last_hidden_state = image_outputs.last_hidden_state + if self.config.vision_use_cls_token: + last_hidden_state = last_hidden_state[:, 1:, :] + image_features = self.multi_modal_projector(last_hidden_state) + image_outputs.pooler_output = image_features + + return image_outputs + + def get_placeholder_mask( + self, + input_ids: torch.LongTensor, + inputs_embeds: torch.FloatTensor, + image_features: torch.FloatTensor | None = None, + video_features: torch.FloatTensor | None = None, + ): + """ + Obtains multimodal placeholder mask from `input_ids` or `inputs_embeds`, and checks that the placeholder token count is + equal to the length of multimodal features. If the lengths are different, an error is raised. + """ + if input_ids is None: + special_image_mask = inputs_embeds == self.get_input_embeddings()( + torch.tensor(self.config.image_token_id, dtype=torch.long, device=inputs_embeds.device) + ) + special_image_mask = special_image_mask.all(-1) + special_video_mask = inputs_embeds == self.get_input_embeddings()( + torch.tensor(self.config.video_token_id, dtype=torch.long, device=inputs_embeds.device) + ) + special_video_mask = special_video_mask.all(-1) + else: + special_image_mask = input_ids == self.config.image_token_id + special_video_mask = input_ids == self.config.video_token_id + + n_image_tokens = special_image_mask.sum() + special_image_mask = special_image_mask.unsqueeze(-1).expand_as(inputs_embeds).to(inputs_embeds.device) + if image_features is not None: + torch_compilable_check( + inputs_embeds[special_image_mask].numel() == image_features.numel(), + f"Image features and image tokens do not match, tokens: {n_image_tokens}, features: {image_features.size()[:-1].numel()}", + ) + + n_video_tokens = special_video_mask.sum() + special_video_mask = special_video_mask.unsqueeze(-1).expand_as(inputs_embeds).to(inputs_embeds.device) + if video_features is not None: + torch_compilable_check( + inputs_embeds[special_video_mask].numel() == video_features.numel(), + f"Video features and video tokens do not match, tokens: {n_video_tokens}, features: {video_features.size()[:-1].numel()}", + ) + return special_image_mask, special_video_mask + + @can_return_tuple + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + pixel_values: torch.FloatTensor | None = None, + pixel_values_videos: torch.FloatTensor | None = None, + attention_mask: torch.Tensor | None = None, + position_ids: torch.LongTensor | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.FloatTensor | None = None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + cache_position: torch.LongTensor | None = None, + logits_to_keep: int | torch.Tensor = 0, + **lm_kwargs, + ) -> tuple | PerceptionLMModelOutputWithPast: + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + if (input_ids is None) ^ (inputs_embeds is not None): + raise ValueError("You must specify exactly one of input_ids or inputs_embeds") + if (pixel_values is not None or pixel_values_videos is not None) and inputs_embeds is not None: + raise ValueError( + "You cannot specify both (pixel_values or pixel_values_videos) and inputs_embeds at the same time, and must specify either one" + ) + + if inputs_embeds is None: + inputs_embeds = self.get_input_embeddings()(input_ids) + + image_features = None + if pixel_values is not None: + image_features = self.get_image_features(pixel_values=pixel_values, return_dict=True).pooler_output + image_features = image_features.to(inputs_embeds.device, dtype=inputs_embeds.dtype) + special_image_mask, _ = self.get_placeholder_mask( + input_ids, inputs_embeds=inputs_embeds, image_features=image_features + ) + inputs_embeds = inputs_embeds.masked_scatter(special_image_mask, image_features) + + video_features = None + if pixel_values_videos is not None: + video_features = self.get_image_features(pixel_values=pixel_values_videos, return_dict=True).pooler_output + video_features = video_features.to(inputs_embeds.device, dtype=inputs_embeds.dtype) + _, special_video_mask = self.get_placeholder_mask( + input_ids, inputs_embeds=inputs_embeds, video_features=video_features + ) + inputs_embeds = inputs_embeds.masked_scatter(special_video_mask, video_features) + + outputs = self.language_model( + attention_mask=attention_mask, + position_ids=position_ids, + past_key_values=past_key_values, + inputs_embeds=inputs_embeds, + use_cache=use_cache, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=True, + cache_position=cache_position, + logits_to_keep=logits_to_keep, + **lm_kwargs, + ) + return PerceptionLMModelOutputWithPast( + last_hidden_state=outputs.last_hidden_state, + hidden_states=outputs.hidden_states, + past_key_values=outputs.past_key_values, + attentions=outputs.attentions, + image_hidden_states=image_features if pixel_values is not None else None, + video_hidden_states=(video_features if pixel_values_videos is not None else None), + ) + + +@auto_docstring +class PerceptionLMForConditionalGeneration(LlavaForConditionalGeneration): + _checkpoint_conversion_mapping = {} + + def prepare_inputs_for_generation( + self, + input_ids, + past_key_values=None, + inputs_embeds=None, + pixel_values=None, + pixel_values_videos=None, + attention_mask=None, + cache_position=None, + logits_to_keep=None, + is_first_iteration=False, + **kwargs, + ): + # Overwritten -- in specific circumstances we don't want to forward image inputs to the model + + model_inputs = super().prepare_inputs_for_generation( + input_ids, + past_key_values=past_key_values, + inputs_embeds=inputs_embeds, + attention_mask=attention_mask, + cache_position=cache_position, + logits_to_keep=logits_to_keep, + is_first_iteration=is_first_iteration, + **kwargs, + ) + + if is_first_iteration or not kwargs.get("use_cache", True): + # Pixel values are used only in the first iteration if available + # In subsequent iterations, they are already merged with text and cached + # NOTE: first iteration doesn't have to be prefill, it can be the first + # iteration with a question and cached system prompt (continue generate from cache) + model_inputs["pixel_values"] = pixel_values + model_inputs["pixel_values_videos"] = pixel_values_videos + return model_inputs + + @can_return_tuple + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + pixel_values: torch.FloatTensor | None = None, + pixel_values_videos: torch.FloatTensor | None = None, + attention_mask: torch.Tensor | None = None, + position_ids: torch.LongTensor | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.FloatTensor | None = None, + labels: torch.LongTensor | None = None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + cache_position: torch.LongTensor | None = None, + logits_to_keep: int | torch.Tensor = 0, + **lm_kwargs, + ) -> tuple | PerceptionLMCausalLMOutputWithPast: + r""" + labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Labels for computing the masked language modeling loss. Indices should either be in `[0, ..., + config.vocab_size]` or -100 (see `input_ids` docstring). Tokens with indices set to `-100` are ignored + (masked), the loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]`. + + Example: + + ```python + from transformers import AutoProcessor, AutoModelForImageTextToText + from huggingface_hub import hf_hub_download + + MODEL_PATH = "facebook/Perception-LM-1B" + processor = AutoProcessor.from_pretrained(MODEL_PATH, use_fast=True) + model = AutoModelForImageTextToText.from_pretrained(MODEL_PATH).to("cuda") + test_image_file = hf_hub_download( + repo_id="shumingh/perception_lm_test_images", + filename="14496_0.PNG", + repo_type="dataset", + ) + conversation = [ + { + "role": "user", + "content": [ + { + "type": "image", + "url": test_image_file, + }, + {"type": "text", "text": "Describe the bar plot in the image."}, + ], + } + ] + + inputs = processor.apply_chat_template( + [conversation], + add_generation_prompt=True, + tokenize=True, + return_dict=True, + return_tensors="pt", + ) + inputs = inputs.to(model.device) + generate_ids = model.generate(**inputs, max_new_tokens=256) + input_length = inputs["input_ids"].shape[1] + generate_ids_without_inputs = generate_ids[:, input_length:] + + for output in processor.batch_decode(generate_ids_without_inputs, skip_special_tokens=True): + print(output) + ```""" + outputs = self.model( + input_ids=input_ids, + pixel_values=pixel_values, + pixel_values_videos=pixel_values_videos, + attention_mask=attention_mask, + position_ids=position_ids, + past_key_values=past_key_values, + inputs_embeds=inputs_embeds, + use_cache=use_cache, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + cache_position=cache_position, + logits_to_keep=logits_to_keep, + **lm_kwargs, + ) + + hidden_states = outputs[0] + # Only compute necessary logits, and do not upcast them to float if we are not computing the loss + slice_indices = slice(-logits_to_keep, None) if isinstance(logits_to_keep, int) else logits_to_keep + logits = self.lm_head(hidden_states[:, slice_indices, :]) + + loss = None + if labels is not None: + loss = self.loss_function( + logits=logits, + labels=labels, + vocab_size=self.config.text_config.vocab_size, + **lm_kwargs, + ) + + return PerceptionLMCausalLMOutputWithPast( + loss=loss, + logits=logits, + past_key_values=outputs.past_key_values, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + image_hidden_states=outputs.image_hidden_states, + video_hidden_states=outputs.video_hidden_states, + ) + + def get_image_features(self, **kwargs): + raise AttributeError("Not needed for PerceptionLM") + + +__all__ = [ + "PerceptionLMForConditionalGeneration", + "PerceptionLMPreTrainedModel", + "PerceptionLMModel", +] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/perception_lm/processing_perception_lm.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/perception_lm/processing_perception_lm.py new file mode 100644 index 0000000000000000000000000000000000000000..0af66b4536733f49dd3f9a3f883cb6cf358bde36 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/perception_lm/processing_perception_lm.py @@ -0,0 +1,202 @@ +# Copyright 2025 Meta Platforms, Inc. and the HuggingFace Inc. team. All rights reserved. +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +""" +Processor class for PerceptionLM. +""" + +from collections.abc import Iterable + +import numpy as np + +from ...feature_extraction_utils import BatchFeature +from ...image_utils import ImageInput, get_image_size, to_numpy_array +from ...processing_utils import MultiModalData, ProcessingKwargs, ProcessorMixin, Unpack +from ...tokenization_utils_base import PreTokenizedInput, TextInput +from ...utils import auto_docstring, logging +from ...video_utils import VideoInput + + +logger = logging.get_logger(__name__) + + +class PerceptionLMProcessorKwargs(ProcessingKwargs, total=False): + _defaults = { + "text_kwargs": { + "padding": False, + "return_mm_token_type_ids": False, + }, + } + + +@auto_docstring +class PerceptionLMProcessor(ProcessorMixin): + def __init__( + self, + video_processor=None, + image_processor=None, + tokenizer=None, + patch_size=None, + chat_template=None, + pooling_ratio=2, + **kwargs, + ): + r""" + patch_size (`int`, *optional*): + Patch size from the vision tower. + pooling_ratio (`int`, *optional*, defaults to 2): + Pooling ratio for vision tokens. If not 1, 2D adaptive pooling is applied over projected vision tokens. + """ + self.patch_size = patch_size + self.pooling_ratio = pooling_ratio + self.image_token = tokenizer.image_token + self.video_token = tokenizer.video_token + self.image_token_id = tokenizer.image_token_id + self.video_token_id = tokenizer.video_token_id + super().__init__(video_processor, image_processor, tokenizer, chat_template=chat_template) + + @auto_docstring + def __call__( + self, + images: ImageInput | None = None, + text: TextInput | PreTokenizedInput | list[TextInput] | list[PreTokenizedInput] = None, + videos: VideoInput | None = None, + **kwargs: Unpack[PerceptionLMProcessorKwargs], + ) -> BatchFeature: + r""" + Returns: + [`BatchFeature`]: A [`BatchFeature`] with the following fields: + + - **input_ids** -- List of token ids to be fed to a model. Returned when `text` is provided. + - **attention_mask** -- List of indices specifying which tokens should be attended to by the model (when + `return_attention_mask=True` or if *"attention_mask"* is in `self.model_input_names` and if `text` is provided). + - **pixel_values** -- Pixel values to be fed to a model. Returned when `images` is provided. + - **pixel_values_videos** -- Video pixel values to be fed to a model. Returned when `videos` is provided. + """ + if text is None: + raise ValueError( + "You have to specify at least `text` input. Optionally, you can also specify `images` or `videos`." + ) + + output_kwargs = self._merge_kwargs( + PerceptionLMProcessorKwargs, + tokenizer_init_kwargs=self.tokenizer.init_kwargs, + **kwargs, + ) + if images is not None: + image_inputs = self.image_processor(images=images, **output_kwargs["images_kwargs"]) + else: + image_inputs = {} + + if videos is not None: + videos_inputs = self.video_processor(videos, **output_kwargs["videos_kwargs"]) + else: + videos_inputs = {} + + if isinstance(text, str): + text = [text] + elif not isinstance(text, list) and not isinstance(text[0], str): + raise TypeError("Invalid input text. Please provide a string, or a list of strings") + + # try to expand inputs in processing if we have the necessary parts + prompt_strings = [] + + pixel_values = iter(image_inputs.get("pixel_values", [])) + pixel_values_videos = iter(videos_inputs.get("pixel_values_videos", [])) + for sample in text: + # Replace the media token with the expanded media token sequence + sample = self._expand_media_tokens(sample, self.tokenizer.image_token, pixel_values) + sample = self._expand_media_tokens(sample, self.tokenizer.video_token, pixel_values_videos) + prompt_strings.append(sample) + + return_tensors = output_kwargs["text_kwargs"].pop("return_tensors", None) + return_mm_token_type_ids = output_kwargs["text_kwargs"].pop("return_mm_token_type_ids", False) + text_inputs = self.tokenizer(prompt_strings, **output_kwargs["text_kwargs"], return_tensors=None) + self._check_special_mm_tokens(prompt_strings, text_inputs, modalities=["image", "video"]) + + if return_mm_token_type_ids: + array_ids = np.array(text_inputs["input_ids"]) + mm_token_type_ids = np.zeros_like(text_inputs["input_ids"]) + mm_token_type_ids[array_ids == self.image_token_id] = 1 + text_inputs["mm_token_type_ids"] = mm_token_type_ids.tolist() + + return BatchFeature(data={**text_inputs, **image_inputs, **videos_inputs}, tensor_type=return_tensors) + + def _expand_media_tokens(self, sample, media_token: str, media_iter: Iterable): + media_count = sample.count(media_token) + if media_count > 0: + media_list = [next(media_iter) for _ in range(media_count)] + sample_splits = sample.split(media_token) + media_token_list = [] + for media in media_list: + height, width = get_image_size(to_numpy_array(media)) + num_tiles = media.shape[0] + num_media_tokens = ( + (height // self.patch_size // self.pooling_ratio) + * (width // self.patch_size // self.pooling_ratio) + * num_tiles + ) + media_token_list.append(num_media_tokens) + sample = "" + for i, num_media_tokens in enumerate(media_token_list): + sample += sample_splits[i] + sample += media_token * num_media_tokens + sample += sample_splits[-1] + return sample + + def _get_num_multimodal_tokens(self, image_sizes=None, **kwargs): + """ + Computes the number of placeholder tokens needed for multimodal inputs with the given sizes. + + Args: + image_sizes (`list[list[int]]`, *optional*): + The input sizes formatted as (height, width) per each image. + + Returns: + `MultiModalData`: A `MultiModalData` object holding number of tokens per each of the provided + input modalities, along with other useful data. + """ + + vision_data = {} + if image_sizes is not None: + images_kwargs = PerceptionLMProcessorKwargs._defaults.get("images_kwargs", {}) + images_kwargs.update(kwargs) + tile_size = images_kwargs.get("tile_size", None) or self.image_processor.tile_size + vision_input_type = images_kwargs.get("vision_input_type", None) or self.image_processor.vision_input_type + + num_image_tokens = [] + num_image_patches = [] + for height, width in image_sizes: + if vision_input_type == "thumb+tile": + aspect_ratio = self.image_processor._fit_image_to_canvas( + img_width=width, img_height=height, tile_size=tile_size + ) + if aspect_ratio is None: + aspect_ratio = self.image_processor._find_closest_aspect_ratio( + img_width=width, img_height=height, tile_size=tile_size + ) + num_tiles = aspect_ratio[0] * aspect_ratio[1] + 1 # base image and tiles + else: + num_tiles = 1 + + num_image_tokens.append( + (tile_size // self.patch_size // self.pooling_ratio) + * (tile_size // self.patch_size // self.pooling_ratio) + * num_tiles + ) + num_image_patches.append(num_tiles) + + vision_data.update({"num_image_tokens": num_image_tokens, "num_image_patches": num_image_patches}) + return MultiModalData(**vision_data) + + +__all__ = ["PerceptionLMProcessor"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/perception_lm/video_processing_perception_lm.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/perception_lm/video_processing_perception_lm.py new file mode 100644 index 0000000000000000000000000000000000000000..aa9d2c16fcb1c3e66cf6d7032aa17f43088f9ef4 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/perception_lm/video_processing_perception_lm.py @@ -0,0 +1,31 @@ +# Copyright 2025 Meta Platforms, Inc. and the HuggingFace Inc. team. All rights reserved. +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""Video processor class for PerceptionLM.""" + +from ...image_utils import IMAGENET_STANDARD_MEAN, IMAGENET_STANDARD_STD, PILImageResampling +from ...video_processing_utils import BaseVideoProcessor + + +class PerceptionLMVideoProcessor(BaseVideoProcessor): + resample = PILImageResampling.BICUBIC + image_mean = IMAGENET_STANDARD_MEAN + image_std = IMAGENET_STANDARD_STD + size = {"height": 448, "width": 448} + do_resize = True + do_center_crop = False + do_rescale = True + do_normalize = True + do_convert_rgb = True + + +__all__ = ["PerceptionLMVideoProcessor"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/persimmon/__init__.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/persimmon/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..cb71eae2547c59a4f9ba7ecbafda56fb9c86b494 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/persimmon/__init__.py @@ -0,0 +1,27 @@ +# Copyright 2024 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from typing import TYPE_CHECKING + +from ...utils import _LazyModule +from ...utils.import_utils import define_import_structure + + +if TYPE_CHECKING: + from .configuration_persimmon import * + from .modeling_persimmon import * +else: + import sys + + _file = globals()["__file__"] + sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__) diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/persimmon/configuration_persimmon.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/persimmon/configuration_persimmon.py new file mode 100644 index 0000000000000000000000000000000000000000..6ab2b9940b037664880fc6b47ca40e9daacf5d87 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/persimmon/configuration_persimmon.py @@ -0,0 +1,128 @@ +# Copyright 2023 Adept AI and the HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""Persimmon model configuration""" + +from ...configuration_utils import PreTrainedConfig +from ...modeling_rope_utils import RopeParameters +from ...utils import logging + + +logger = logging.get_logger(__name__) + + +class PersimmonConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`PersimmonModel`]. It is used to instantiate an + Persimmon model according to the specified arguments, defining the model architecture. Instantiating a + configuration with the defaults will yield a similar configuration to that of the + [adept/persimmon-8b-base](https://huggingface.co/adept/persimmon-8b-base). + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + + Args: + vocab_size (`int`, *optional*, defaults to 262144): + Vocabulary size of the Persimmon model. Defines the number of different tokens that can be represented by + the `inputs_ids` passed when calling [`PersimmonModel`] + hidden_size (`int`, *optional*, defaults to 4096): + Dimension of the hidden representations. + intermediate_size (`int`, *optional*, defaults to 16384): + Dimension of the MLP representations. + num_hidden_layers (`int`, *optional*, defaults to 36): + Number of hidden layers in the Transformer encoder. + num_attention_heads (`int`, *optional*, defaults to 64): + Number of attention heads for each attention layer in the Transformer encoder. + hidden_act (`str` or `function`, *optional*, defaults to `"relu2"`): + The non-linear activation function (function or string) in the decoder. + max_position_embeddings (`int`, *optional*, defaults to 16384): + The maximum sequence length that this model might ever be used with. + initializer_range (`float`, *optional*, defaults to 0.02): + The standard deviation of the truncated_normal_initializer for initializing all weight matrices. + layer_norm_eps (`float`, *optional*, defaults to 1e-5): + The epsilon used by the rms normalization layers. + use_cache (`bool`, *optional*, defaults to `True`): + Whether or not the model should return the last key/values attentions (not used by all models). Only + relevant if `config.is_decoder=True`. + tie_word_embeddings(`bool`, *optional*, defaults to `False`): + Whether to tie weight embeddings + rope_parameters (`RopeParameters`, *optional*): + Dictionary containing the configuration parameters for the RoPE embeddings. The dictionary should contain + a value for `rope_theta` and optionally parameters used for scaling in case you want to use RoPE + with longer `max_position_embeddings`. + qk_layernorm (`bool`, *optional*, default to `True`): + Whether or not to normalize the Queries and Keys after projecting the hidden states + hidden_dropout (`float`, *optional*, default to 0.0): + The dropout ratio after applying the MLP to the hidden states. + attention_dropout (`float`, *optional*, default to 0.0): + The dropout ratio after computing the attention scores. + + Example: + + ```python + >>> from transformers import PersimmonModel, PersimmonConfig + + >>> # Initializing a Persimmon persimmon-7b style configuration + >>> configuration = PersimmonConfig() + ```""" + + model_type = "persimmon" + keys_to_ignore_at_inference = ["past_key_values"] + + def __init__( + self, + vocab_size: int | None = 262144, + hidden_size: int | None = 4096, + intermediate_size: int | None = 16384, + num_hidden_layers: int | None = 36, + num_attention_heads: int | None = 64, + hidden_act: str | None = "relu2", + max_position_embeddings: int | None = 16384, + initializer_range: float | None = 0.02, + layer_norm_eps: int | None = 1e-5, + use_cache: bool | None = True, + tie_word_embeddings: bool | None = False, + rope_parameters: RopeParameters | dict[str, RopeParameters] | None = None, + qk_layernorm: bool | None = True, + hidden_dropout: float | None = 0.0, + attention_dropout: float | None = 0.0, + pad_token_id: int | None = None, + bos_token_id: int | None = 1, + eos_token_id: int | None = 2, + **kwargs, + ): + self.vocab_size = vocab_size + self.max_position_embeddings = max_position_embeddings + self.hidden_size = hidden_size + self.intermediate_size = intermediate_size + self.num_hidden_layers = num_hidden_layers + self.num_attention_heads = num_attention_heads + self.hidden_act = hidden_act + self.initializer_range = initializer_range + self.layer_norm_eps = layer_norm_eps + self.use_cache = use_cache + self.qk_layernorm = qk_layernorm + self.hidden_dropout = hidden_dropout + self.attention_dropout = attention_dropout + self.rope_parameters = rope_parameters + kwargs.setdefault("partial_rotary_factor", 0.5) # assign default for BC + + self.tie_word_embeddings = tie_word_embeddings + self.pad_token_id = pad_token_id + self.bos_token_id = bos_token_id + self.eos_token_id = eos_token_id + super().__init__(**kwargs) + + +__all__ = ["PersimmonConfig"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/persimmon/modeling_persimmon.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/persimmon/modeling_persimmon.py new file mode 100644 index 0000000000000000000000000000000000000000..ce985c2b6272d26e3345f130fd620195aad115dd --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/persimmon/modeling_persimmon.py @@ -0,0 +1,650 @@ +# Copyright 2023 EleutherAI and the HuggingFace Inc. team. All rights reserved. +# +# This code is based on EleutherAI's GPT-NeoX library and the GPT-NeoX +# and OPT implementations in this library. It has been modified from its +# original forms to accommodate minor architectural differences compared +# to GPT-NeoX and OPT used by the Meta AI team that trained the model. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""PyTorch Persimmon model.""" + +from collections.abc import Callable +from typing import Optional + +import torch +from torch import nn + +from ...activations import ACT2FN +from ...cache_utils import Cache, DynamicCache +from ...generation import GenerationMixin +from ...masking_utils import create_causal_mask +from ...modeling_flash_attention_utils import FlashAttentionKwargs +from ...modeling_layers import ( + GenericForSequenceClassification, + GenericForTokenClassification, + GradientCheckpointingLayer, +) +from ...modeling_outputs import ( + BaseModelOutputWithPast, + CausalLMOutputWithPast, +) +from ...modeling_rope_utils import ( + ROPE_INIT_FUNCTIONS, + dynamic_rope_update, +) +from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel +from ...processing_utils import Unpack +from ...utils import auto_docstring, can_return_tuple, logging +from ...utils.generic import maybe_autocast +from .configuration_persimmon import PersimmonConfig + + +logger = logging.get_logger(__name__) + + +# Copied from transformers.models.llama.modeling_llama.LlamaRotaryEmbedding with Llama->Persimmon +class PersimmonRotaryEmbedding(nn.Module): + inv_freq: torch.Tensor # fix linting for `register_buffer` + + def __init__(self, config: PersimmonConfig, device=None): + super().__init__() + self.max_seq_len_cached = config.max_position_embeddings + self.original_max_seq_len = config.max_position_embeddings + + self.config = config + + self.rope_type = self.config.rope_parameters["rope_type"] + rope_init_fn: Callable = self.compute_default_rope_parameters + if self.rope_type != "default": + rope_init_fn = ROPE_INIT_FUNCTIONS[self.rope_type] + inv_freq, self.attention_scaling = rope_init_fn(self.config, device) + + self.register_buffer("inv_freq", inv_freq, persistent=False) + self.register_buffer("original_inv_freq", inv_freq.clone(), persistent=False) + + @staticmethod + # Ignore copy + def compute_default_rope_parameters( + config: PersimmonConfig | None = None, + device: Optional["torch.device"] = None, + seq_len: int | None = None, + ) -> tuple["torch.Tensor", float]: + """ + Computes the inverse frequencies according to the original RoPE implementation + Args: + config ([`~transformers.PreTrainedConfig`]): + The model configuration. + device (`torch.device`): + The device to use for initialization of the inverse frequencies. + seq_len (`int`, *optional*): + The current sequence length. Unused for this type of RoPE. + Returns: + Tuple of (`torch.Tensor`, `float`), containing the inverse frequencies for the RoPE embeddings and the + post-processing scaling factor applied to the computed cos/sin (unused in this type of RoPE). + """ + base = config.rope_parameters["rope_theta"] + partial_rotary_factor = config.rope_parameters.get("partial_rotary_factor", 1.0) + head_dim = getattr(config, "head_dim", None) or config.hidden_size // config.num_attention_heads + dim = int(head_dim * partial_rotary_factor) + + attention_factor = 1.0 # Unused in this type of RoPE + + # Compute the inverse frequencies + inv_freq = 1.0 / ( + base ** (torch.arange(0, dim, 2, dtype=torch.int64).to(device=device, dtype=torch.float) / dim) + ) + return inv_freq, attention_factor + + @torch.no_grad() + @dynamic_rope_update # power user: used with advanced RoPE types (e.g. dynamic rope) + def forward(self, x, position_ids): + inv_freq_expanded = self.inv_freq[None, :, None].float().expand(position_ids.shape[0], -1, 1).to(x.device) + position_ids_expanded = position_ids[:, None, :].float() + + device_type = x.device.type if isinstance(x.device.type, str) and x.device.type != "mps" else "cpu" + with maybe_autocast(device_type=device_type, enabled=False): # Force float32 + freqs = (inv_freq_expanded.float() @ position_ids_expanded.float()).transpose(1, 2) + emb = torch.cat((freqs, freqs), dim=-1) + cos = emb.cos() * self.attention_scaling + sin = emb.sin() * self.attention_scaling + + return cos.to(dtype=x.dtype), sin.to(dtype=x.dtype) + + +# Copied from transformers.models.llama.modeling_llama.rotate_half +def rotate_half(x): + """Rotates half the hidden dims of the input.""" + x1 = x[..., : x.shape[-1] // 2] + x2 = x[..., x.shape[-1] // 2 :] + return torch.cat((-x2, x1), dim=-1) + + +# Copied from transformers.models.llama.modeling_llama.apply_rotary_pos_emb +def apply_rotary_pos_emb(q, k, cos, sin, unsqueeze_dim=1): + """Applies Rotary Position Embedding to the query and key tensors. + + Args: + q (`torch.Tensor`): The query tensor. + k (`torch.Tensor`): The key tensor. + cos (`torch.Tensor`): The cosine part of the rotary embedding. + sin (`torch.Tensor`): The sine part of the rotary embedding. + unsqueeze_dim (`int`, *optional*, defaults to 1): + The 'unsqueeze_dim' argument specifies the dimension along which to unsqueeze cos[position_ids] and + sin[position_ids] so that they can be properly broadcasted to the dimensions of q and k. For example, note + that cos[position_ids] and sin[position_ids] have the shape [batch_size, seq_len, head_dim]. Then, if q and + k have the shape [batch_size, heads, seq_len, head_dim], then setting unsqueeze_dim=1 makes + cos[position_ids] and sin[position_ids] broadcastable to the shapes of q and k. Similarly, if q and k have + the shape [batch_size, seq_len, heads, head_dim], then set unsqueeze_dim=2. + Returns: + `tuple(torch.Tensor)` comprising of the query and key tensors rotated using the Rotary Position Embedding. + """ + cos = cos.unsqueeze(unsqueeze_dim) + sin = sin.unsqueeze(unsqueeze_dim) + q_embed = (q * cos) + (rotate_half(q) * sin) + k_embed = (k * cos) + (rotate_half(k) * sin) + return q_embed, k_embed + + +# Copied from transformers.models.gpt_neox.modeling_gpt_neox.GPTNeoXMLP with GPTNeoX->Persimmon +class PersimmonMLP(nn.Module): + def __init__(self, config): + super().__init__() + self.dense_h_to_4h = nn.Linear(config.hidden_size, config.intermediate_size) + self.dense_4h_to_h = nn.Linear(config.intermediate_size, config.hidden_size) + self.act = ACT2FN[config.hidden_act] + + def forward(self, hidden_states): + hidden_states = self.dense_h_to_4h(hidden_states) + hidden_states = self.act(hidden_states) + hidden_states = self.dense_4h_to_h(hidden_states) + return hidden_states + + +def eager_attention_forward( + module: nn.Module, + query: torch.Tensor, + key: torch.Tensor, + value: torch.Tensor, + attention_mask: torch.Tensor | None, + scaling: float, + dropout: float = 0.0, + **kwargs, +): + attn_weights = torch.matmul(query, key.transpose(2, 3)) * scaling + if attention_mask is not None: + attn_weights = attn_weights + attention_mask + + attn_weights = nn.functional.softmax(attn_weights, dim=-1, dtype=torch.float32).to(query.dtype) + attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training) + attn_output = torch.matmul(attn_weights, value) + attn_output = attn_output.transpose(1, 2).contiguous() + + return attn_output, attn_weights + + +class PersimmonAttention(nn.Module): + """Multi-headed attention from 'Attention Is All You Need' paper""" + + def __init__(self, config: PersimmonConfig, layer_idx: int | None = None): + super().__init__() + self.config = config + self.layer_idx = layer_idx + if layer_idx is None: + logger.warning_once( + f"Instantiating {self.__class__.__name__} without passing a `layer_idx` is not recommended and will " + "lead to errors during the forward call if caching is used. Please make sure to provide a `layer_idx` " + "when creating this class." + ) + + self.hidden_size = config.hidden_size + self.num_heads = config.num_attention_heads + self.head_dim = self.hidden_size // self.num_heads + + self.rotary_ndims = int(self.head_dim * config.rope_parameters["partial_rotary_factor"]) + self.is_causal = True + + if (self.head_dim * self.num_heads) != self.hidden_size: + raise ValueError( + f"hidden_size must be divisible by num_heads (got `hidden_size`: {self.hidden_size}" + f" and `num_heads`: {self.num_heads})." + ) + self.query_key_value = nn.Linear(self.hidden_size, 3 * self.hidden_size, bias=True) + self.dense = nn.Linear(self.num_heads * self.head_dim, self.hidden_size, bias=True) + self.qk_layernorm = config.qk_layernorm + self.scaling = self.head_dim**-0.5 + + if self.qk_layernorm: + self.q_layernorm = nn.LayerNorm( + config.hidden_size // self.num_heads, eps=config.layer_norm_eps, elementwise_affine=True + ) + self.k_layernorm = nn.LayerNorm( + config.hidden_size // self.num_heads, eps=config.layer_norm_eps, elementwise_affine=True + ) + self.attention_dropout = nn.Dropout(config.attention_dropout) + + def _split_heads(self, fused_qkv: torch.Tensor) -> tuple[torch.Tensor, torch.Tensor, torch.Tensor]: + """ + Split the last dimension into (num_heads, head_dim) without making any copies, results share same memory + storage as `fused_qkv` + + Args: + fused_qkv (`torch.tensor`): [batch_size, seq_length, num_heads * 3 * head_dim] + + Returns: + query: [batch_size, seq_length, num_heads, head_dim] key: [batch_size, seq_length, num_heads, head_dim] + value: [batch_size, seq_length, num_heads, head_dim] + """ + batch_size, seq_length, three_times_hidden_size = fused_qkv.shape + fused_qkv = fused_qkv.view(batch_size, seq_length, self.num_heads, 3, self.head_dim) + return fused_qkv[..., 0, :], fused_qkv[..., 1, :], fused_qkv[..., 2, :] + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.Tensor | None = None, + position_ids: torch.LongTensor | None = None, + past_key_values: Cache | None = None, + output_attentions: bool = False, + use_cache: bool = False, + cache_position: torch.LongTensor | None = None, + position_embeddings: tuple[torch.Tensor, torch.Tensor] | None = None, + **kwargs: Unpack[FlashAttentionKwargs], + ) -> tuple[torch.Tensor, torch.Tensor | None, tuple[torch.Tensor] | None]: + bsz, q_len, _ = hidden_states.size() + + # [batch_size, seq_length, 3 x hidden_size] + fused_qkv = self.query_key_value(hidden_states) + + # 3 x [batch_size, seq_length, num_heads, head_dim] + (query_states, key_states, value_states) = self._split_heads(fused_qkv) + + if self.qk_layernorm: + query_states = self.q_layernorm(query_states) + key_states = self.k_layernorm(key_states) + + # [batch_size, num_heads, seq_length, head_dim] -> [batch_size, seq_length, num_heads, head_dim] + query_states = query_states.transpose(1, 2) + value_states = value_states.transpose(1, 2) + key_states = key_states.transpose(1, 2) + + cos, sin = position_embeddings + query_rot, query_pass = ( + query_states[..., : self.rotary_ndims], + query_states[..., self.rotary_ndims :], + ) + key_rot, key_pass = ( + key_states[..., : self.rotary_ndims], + key_states[..., self.rotary_ndims :], + ) + # [batch_size, seq_length, num_heads, head_dim // config.partial_rotary_factor] + query_rot, key_rot = apply_rotary_pos_emb(query_rot, key_rot, cos, sin) + + # [batch_size, seq_length, num_heads, head_dim] + query_states = torch.cat((query_rot, query_pass), dim=-1) + key_states = torch.cat((key_rot, key_pass), dim=-1) + + if past_key_values is not None: + # Specific to RoPE models with partial rotation + cache_kwargs = { + "sin": sin, + "cos": cos, + "partial_rotation_size": self.rotary_ndims, + "cache_position": cache_position, + } + key_states, value_states = past_key_values.update(key_states, value_states, self.layer_idx, cache_kwargs) + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, eager_attention_forward + ) + + attn_output, attn_weights = attention_interface( + self, + query_states, + key_states, + value_states, + attention_mask, + dropout=0.0 if not self.training else self.config.attention_dropout, + scaling=self.scaling, + **kwargs, + ) + + attn_output = attn_output.reshape(bsz, q_len, -1) + attn_output = self.dense(attn_output) + + if not output_attentions: + attn_weights = None + + return attn_output, attn_weights + + +class PersimmonDecoderLayer(GradientCheckpointingLayer): + def __init__(self, config: PersimmonConfig, layer_idx: int): + super().__init__() + self.hidden_size = config.hidden_size + self.self_attn = PersimmonAttention(config=config, layer_idx=layer_idx) + self.mlp = PersimmonMLP(config) + self.input_layernorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps) + self.post_attention_layernorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps) + self.dropout = nn.Dropout(config.hidden_dropout) + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.Tensor | None = None, + position_ids: torch.LongTensor | None = None, + past_key_values: Cache | None = None, + output_attentions: bool | None = False, + use_cache: bool | None = False, + cache_position: torch.LongTensor | None = None, + position_embeddings: tuple[torch.Tensor, torch.Tensor] | None = None, + **kwargs: Unpack[FlashAttentionKwargs], + ) -> tuple[torch.FloatTensor, tuple[torch.FloatTensor, torch.FloatTensor] | None]: + """ + Args: + hidden_states (`torch.FloatTensor`): input to the layer of shape `(batch, seq_len, embed_dim)` + attention_mask (`torch.FloatTensor`, *optional*): attention mask of size + `(batch, 1, tgt_len, src_len)` where padding elements are indicated by very large negative values. + position_ids (`torch.LongTensor` of shape `({0})`, *optional*): + Indices of positions of each input sequence tokens in the position embeddings. Selected in the range + `[0, config.n_positions - 1]`. + [What are position IDs?](../glossary#position-ids) + past_key_values (`Cache`, *optional*): + cached past key and value projection states + output_attentions (`bool`, *optional*): + Whether or not to return the attentions tensors of all attention layers. See `attentions` under + returned tensors for more detail. + use_cache (`bool`, *optional*): + If set to `True`, `past_key_values` key value states are returned and can be used to speed up decoding + (see `past_key_values`). + cache_position (`torch.LongTensor` of shape `(sequence_length)`, *optional*): + Indices depicting the position of the input sequence tokens in the sequence + position_embeddings (`tuple[torch.FloatTensor, torch.FloatTensor]`, *optional*): + Tuple containing the cosine and sine positional embeddings of shape `(batch_size, seq_len, head_dim)`, + with `head_dim` being the embedding dimension of each attention head. + """ + + residual = hidden_states + + hidden_states = self.input_layernorm(hidden_states) + + # Self Attention + hidden_states, self_attn_weights = self.self_attn( + hidden_states=hidden_states, + attention_mask=attention_mask, + position_ids=position_ids, + past_key_values=past_key_values, + output_attentions=output_attentions, + use_cache=use_cache, + cache_position=cache_position, + position_embeddings=position_embeddings, + **kwargs, + ) + hidden_states = residual + hidden_states + + # Fully Connected + residual = hidden_states + hidden_states = self.post_attention_layernorm(hidden_states) + hidden_states = self.mlp(hidden_states) + + hidden_states = self.dropout(hidden_states) + hidden_states = hidden_states + residual + + outputs = (hidden_states,) + + if output_attentions: + outputs += (self_attn_weights,) + + return outputs + + +@auto_docstring +class PersimmonPreTrainedModel(PreTrainedModel): + config: PersimmonConfig + base_model_prefix = "model" + supports_gradient_checkpointing = True + _no_split_modules = ["PersimmonDecoderLayer"] + _skip_keys_device_placement = "past_key_values" + _can_compile_fullgraph = True + _supports_sdpa = True + _supports_flash_attn = True + _supports_attention_backend = True + + +@auto_docstring +class PersimmonModel(PersimmonPreTrainedModel): + """ + Transformer decoder consisting of *config.num_hidden_layers* layers. Each layer is a [`PersimmonDecoderLayer`] + + Args: + config: PersimmonConfig + """ + + def __init__(self, config: PersimmonConfig): + super().__init__(config) + self.padding_idx = config.pad_token_id + self.vocab_size = config.vocab_size + + self.embed_tokens = nn.Embedding(config.vocab_size, config.hidden_size, self.padding_idx) + self.layers = nn.ModuleList( + [PersimmonDecoderLayer(config, layer_idx) for layer_idx in range(config.num_hidden_layers)] + ) + self.final_layernorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps) + self.rotary_emb = PersimmonRotaryEmbedding(config=self.config) + self.gradient_checkpointing = False + # Initialize weights and apply final processing + self.post_init() + + @can_return_tuple + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.Tensor | None = None, + position_ids: torch.LongTensor | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.FloatTensor | None = None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + cache_position: torch.LongTensor | None = None, + **kwargs: Unpack[FlashAttentionKwargs], + ) -> BaseModelOutputWithPast: + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + use_cache = use_cache if use_cache is not None else self.config.use_cache + + if (input_ids is None) ^ (inputs_embeds is not None): + raise ValueError("You must specify exactly one of input_ids or inputs_embeds") + + if self.gradient_checkpointing and self.training: + if use_cache: + logger.warning_once( + "`use_cache=True` is incompatible with gradient checkpointing. Setting `use_cache=False`..." + ) + use_cache = False + + if use_cache and past_key_values is None: + past_key_values = DynamicCache(config=self.config) + + if inputs_embeds is None: + inputs_embeds = self.embed_tokens(input_ids) + + if cache_position is None: + past_seen_tokens = past_key_values.get_seq_length() if past_key_values is not None else 0 + cache_position = torch.arange( + past_seen_tokens, past_seen_tokens + inputs_embeds.shape[1], device=inputs_embeds.device + ) + if position_ids is None: + position_ids = cache_position.unsqueeze(0) + + causal_mask = create_causal_mask( + config=self.config, + inputs_embeds=inputs_embeds, + attention_mask=attention_mask, + cache_position=cache_position, + past_key_values=past_key_values, + position_ids=position_ids, + ) + + hidden_states = inputs_embeds + position_embeddings = self.rotary_emb(hidden_states, position_ids=position_ids) + + # decoder layers + all_hidden_states = () if output_hidden_states else None + all_self_attns = () if output_attentions else None + + for decoder_layer in self.layers: + if output_hidden_states: + all_hidden_states += (hidden_states,) + + layer_outputs = decoder_layer( + hidden_states, + attention_mask=causal_mask, + position_ids=position_ids, + past_key_values=past_key_values, + output_attentions=output_attentions, + use_cache=use_cache, + cache_position=cache_position, + position_embeddings=position_embeddings, + **kwargs, + ) + + hidden_states = layer_outputs[0] + + if output_attentions: + all_self_attns += (layer_outputs[1],) + + hidden_states = self.final_layernorm(hidden_states) + + # add hidden states from the last decoder layer + if output_hidden_states: + all_hidden_states += (hidden_states,) + + return BaseModelOutputWithPast( + last_hidden_state=hidden_states, + past_key_values=past_key_values, + hidden_states=all_hidden_states, + attentions=all_self_attns, + ) + + +class PersimmonForCausalLM(PersimmonPreTrainedModel, GenerationMixin): + _tied_weights_keys = {"lm_head.weight": "model.embed_tokens.weight"} + + # Copied from transformers.models.llama.modeling_llama.LlamaForCausalLM.__init__ with LLAMA->PERSIMMON,Llama->Persimmon + def __init__(self, config): + super().__init__(config) + self.model = PersimmonModel(config) + self.vocab_size = config.vocab_size + self.lm_head = nn.Linear(config.hidden_size, config.vocab_size, bias=False) + + # Initialize weights and apply final processing + self.post_init() + + @can_return_tuple + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.Tensor | None = None, + position_ids: torch.LongTensor | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.FloatTensor | None = None, + labels: torch.LongTensor | None = None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + cache_position: torch.LongTensor | None = None, + logits_to_keep: int | torch.Tensor = 0, + **kwargs, + ) -> CausalLMOutputWithPast: + r""" + labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Labels for computing the masked language modeling loss. Indices should either be in `[0, ..., + config.vocab_size]` or -100 (see `input_ids` docstring). Tokens with indices set to `-100` are ignored + (masked), the loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]`. + + Example: + + ```python + >>> from transformers import AutoTokenizer, PersimmonForCausalLM + + >>> model = PersimmonForCausalLM.from_pretrained("adept/persimmon-8b-base") + >>> tokenizer = AutoTokenizer.from_pretrained("adept/persimmon-8b-base") + + >>> prompt = "human: Hey, what should I eat for dinner?" + >>> inputs = tokenizer(prompt, return_tensors="pt") + + >>> # Generate + >>> generate_ids = model.generate(inputs.input_ids, max_length=30) + >>> tokenizer.batch_decode(generate_ids, skip_special_tokens=True, clean_up_tokenization_spaces=False)[0] + 'human: Hey, what should I eat for dinner?\n\ncat: 🐱\n\nhuman: 😐\n\n' + ```""" + + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + + # decoder outputs consists of (dec_features, layer_state, dec_hidden, dec_attn) + outputs: BaseModelOutputWithPast = self.model( + input_ids=input_ids, + attention_mask=attention_mask, + position_ids=position_ids, + past_key_values=past_key_values, + inputs_embeds=inputs_embeds, + use_cache=use_cache, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + cache_position=cache_position, + **kwargs, + ) + + hidden_states = outputs.last_hidden_state + # No upscaling to float was ever done for Persimmon + slice_indices = slice(-logits_to_keep, None) if isinstance(logits_to_keep, int) else logits_to_keep + logits = self.lm_head(hidden_states[:, slice_indices, :]) + + loss = None + if labels is not None: + loss = self.loss_function( + logits, + labels, + vocab_size=self.config.vocab_size, + **kwargs, + ) + + return CausalLMOutputWithPast( + loss=loss, + logits=logits, + past_key_values=outputs.past_key_values, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + ) + + +class PersimmonForSequenceClassification(GenericForSequenceClassification, PersimmonPreTrainedModel): ... + + +class PersimmonForTokenClassification(GenericForTokenClassification, PersimmonPreTrainedModel): ... + + +__all__ = [ + "PersimmonForCausalLM", + "PersimmonModel", + "PersimmonPreTrainedModel", + "PersimmonForSequenceClassification", + "PersimmonForTokenClassification", +] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/phi/__init__.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/phi/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..cffe33da73ee42eb20a2e7f33ea9351bb7da75c2 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/phi/__init__.py @@ -0,0 +1,27 @@ +# Copyright 2023 Microsoft and The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from typing import TYPE_CHECKING + +from ...utils import _LazyModule +from ...utils.import_utils import define_import_structure + + +if TYPE_CHECKING: + from .configuration_phi import * + from .modeling_phi import * +else: + import sys + + _file = globals()["__file__"] + sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__) diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/phi/configuration_phi.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/phi/configuration_phi.py new file mode 100644 index 0000000000000000000000000000000000000000..eca01d456f777793e533e5c58f8135f9d0116286 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/phi/configuration_phi.py @@ -0,0 +1,173 @@ +# Copyright 2023 Microsoft and the HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +"""Phi model configuration""" + +from ...configuration_utils import PreTrainedConfig +from ...modeling_rope_utils import RopeParameters +from ...utils import logging + + +logger = logging.get_logger(__name__) + + +class PhiConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`PhiModel`]. It is used to instantiate an Phi + model according to the specified arguments, defining the model architecture. Instantiating a configuration with the + defaults will yield a similar configuration to that of the Phi + [microsoft/phi-1](https://huggingface.co/microsoft/phi-1). + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + vocab_size (`int`, *optional*, defaults to 51200): + Vocabulary size of the Phi model. Defines the number of different tokens that can be represented by the + `inputs_ids` passed when calling [`PhiModel`]. + hidden_size (`int`, *optional*, defaults to 2048): + Dimension of the hidden representations. + intermediate_size (`int`, *optional*, defaults to 8192): + Dimension of the MLP representations. + num_hidden_layers (`int`, *optional*, defaults to 24): + Number of hidden layers in the Transformer decoder. + num_attention_heads (`int`, *optional*, defaults to 32): + Number of attention heads for each attention layer in the Transformer decoder. + num_key_value_heads (`int`, *optional*): + This is the number of key_value heads that should be used to implement Grouped Query Attention. If + `num_key_value_heads=num_attention_heads`, the model will use Multi Head Attention (MHA), if + `num_key_value_heads=1` the model will use Multi Query Attention (MQA) otherwise GQA is used. When + converting a multi-head checkpoint to a GQA checkpoint, each group key and value head should be constructed + by meanpooling all the original heads within that group. For more details, check out [this + paper](https://huggingface.co/papers/2305.13245). If it is not specified, will default to + `num_attention_heads`. + resid_pdrop (`float`, *optional*, defaults to 0.0): + Dropout probability for mlp outputs. + embd_pdrop (`int`, *optional*, defaults to 0.0): + The dropout ratio for the embeddings. + attention_dropout (`float`, *optional*, defaults to 0.0): + The dropout ratio after computing the attention scores. + hidden_act (`str` or `function`, *optional*, defaults to `"gelu_new"`): + The non-linear activation function (function or string) in the decoder. + max_position_embeddings (`int`, *optional*, defaults to 2048): + The maximum sequence length that this model might ever be used with. Phi-1 and Phi-1.5 supports up to 2048 + tokens. + initializer_range (`float`, *optional*, defaults to 0.02): + The standard deviation of the truncated_normal_initializer for initializing all weight matrices. + layer_norm_eps (`float`, *optional*, defaults to 1e-05): + The epsilon used by the rms normalization layers. + use_cache (`bool`, *optional*, defaults to `True`): + Whether or not the model should return the last key/values attentions (not used by all models). Only + relevant if `config.is_decoder=True`. Whether to tie weight embeddings or not. + tie_word_embeddings (`bool`, *optional*, defaults to `False`): + Whether to tie weight embeddings + rope_parameters (`RopeParameters`, *optional*): + Dictionary containing the configuration parameters for the RoPE embeddings. The dictionary should contain + a value for `rope_theta` and optionally parameters used for scaling in case you want to use RoPE + with longer `max_position_embeddings`. + qk_layernorm (`bool`, *optional*, defaults to `False`): + Whether or not to normalize the Queries and Keys after projecting the hidden states. + bos_token_id (`int`, *optional*, defaults to 1): + Denotes beginning of sequences token id. + eos_token_id (`int`, *optional*, defaults to 2): + Denotes end of sequences token id. + pad_token_id (`int`, *optional*): + The id of the padding token. + + Example: + + ```python + >>> from transformers import PhiModel, PhiConfig + + >>> # Initializing a Phi-1 style configuration + >>> configuration = PhiConfig.from_pretrained("microsoft/phi-1") + + >>> # Initializing a model from the configuration + >>> model = PhiModel(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "phi" + keys_to_ignore_at_inference = ["past_key_values"] + base_model_tp_plan = { + "layers.*.self_attn.q_proj": "colwise", + "layers.*.self_attn.k_proj": "colwise", + "layers.*.self_attn.v_proj": "colwise", + "layers.*.self_attn.dense": "rowwise", + "layers.*.mlp.fc1": "colwise", + "layers.*.mlp.fc2": "rowwise", + } + base_model_pp_plan = { + "embed_tokens": (["input_ids"], ["inputs_embeds"]), + "embed_dropout": (["inputs_embeds"], ["inputs_embeds"]), + "layers": (["hidden_states", "attention_mask"], ["hidden_states"]), + "final_layernorm": (["hidden_states"], ["hidden_states"]), + } + + def __init__( + self, + vocab_size: int | None = 51200, + hidden_size: int | None = 2048, + intermediate_size: int | None = 8192, + num_hidden_layers: int | None = 24, + num_attention_heads: int | None = 32, + num_key_value_heads: int | None = None, + resid_pdrop: float | None = 0.0, + embd_pdrop: float | None = 0.0, + attention_dropout: float | None = 0.0, + hidden_act: str | None = "gelu_new", + max_position_embeddings: int | None = 2048, + initializer_range: float | None = 0.02, + layer_norm_eps: int | None = 1e-5, + use_cache: bool | None = True, + tie_word_embeddings: bool | None = False, + rope_parameters: RopeParameters | dict[str, RopeParameters] | None = None, + qk_layernorm: bool | None = False, + bos_token_id: int | None = 1, + eos_token_id: int | None = 2, + pad_token_id: int | None = None, + **kwargs, + ): + self.vocab_size = vocab_size + self.hidden_size = hidden_size + self.intermediate_size = intermediate_size + self.num_hidden_layers = num_hidden_layers + self.num_attention_heads = num_attention_heads + + if num_key_value_heads is None: + num_key_value_heads = num_attention_heads + + self.num_key_value_heads = num_key_value_heads + self.resid_pdrop = resid_pdrop + self.embd_pdrop = embd_pdrop + self.attention_dropout = attention_dropout + self.hidden_act = hidden_act + self.max_position_embeddings = max_position_embeddings + self.initializer_range = initializer_range + self.layer_norm_eps = layer_norm_eps + self.use_cache = use_cache + self.qk_layernorm = qk_layernorm + self.rope_parameters = rope_parameters + kwargs.setdefault("partial_rotary_factor", 0.5) # assign default for BC + + self.bos_token_id = bos_token_id + self.eos_token_id = eos_token_id + self.pad_token_id = pad_token_id + self.tie_word_embeddings = tie_word_embeddings + super().__init__(**kwargs) + + +__all__ = ["PhiConfig"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/phi/modeling_phi.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/phi/modeling_phi.py new file mode 100644 index 0000000000000000000000000000000000000000..cdf24e069c77f622af17c5b6999a7cf2fe36883c --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/phi/modeling_phi.py @@ -0,0 +1,551 @@ +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# This file was automatically generated from src/transformers/models/phi/modular_phi.py. +# Do NOT edit this file manually as any edits will be overwritten by the generation of +# the file from the modular. If any change should be done, please apply the change to the +# modular_phi.py file directly. One of our CI enforces this. +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +from collections.abc import Callable +from typing import Optional + +import torch +import torch.nn as nn + +from ...activations import ACT2FN +from ...cache_utils import Cache, DynamicCache +from ...generation import GenerationMixin +from ...integrations import use_kernel_func_from_hub, use_kernelized_func +from ...masking_utils import create_causal_mask +from ...modeling_layers import ( + GenericForSequenceClassification, + GenericForTokenClassification, + GradientCheckpointingLayer, +) +from ...modeling_outputs import BaseModelOutputWithPast, CausalLMOutputWithPast +from ...modeling_rope_utils import ROPE_INIT_FUNCTIONS, dynamic_rope_update +from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel +from ...processing_utils import Unpack +from ...utils import TransformersKwargs, auto_docstring, logging +from ...utils.generic import can_return_tuple, maybe_autocast, merge_with_config_defaults +from ...utils.output_capturing import capture_outputs +from .configuration_phi import PhiConfig + + +logger = logging.get_logger(__name__) + + +class PhiRotaryEmbedding(nn.Module): + inv_freq: torch.Tensor # fix linting for `register_buffer` + + def __init__(self, config: PhiConfig, device=None): + super().__init__() + self.max_seq_len_cached = config.max_position_embeddings + self.original_max_seq_len = config.max_position_embeddings + + self.config = config + + self.rope_type = self.config.rope_parameters["rope_type"] + rope_init_fn: Callable = self.compute_default_rope_parameters + if self.rope_type != "default": + rope_init_fn = ROPE_INIT_FUNCTIONS[self.rope_type] + inv_freq, self.attention_scaling = rope_init_fn(self.config, device) + + self.register_buffer("inv_freq", inv_freq, persistent=False) + self.register_buffer("original_inv_freq", inv_freq.clone(), persistent=False) + + @staticmethod + def compute_default_rope_parameters( + config: PhiConfig | None = None, + device: Optional["torch.device"] = None, + seq_len: int | None = None, + ) -> tuple["torch.Tensor", float]: + """ + Computes the inverse frequencies according to the original RoPE implementation + Args: + config ([`~transformers.PreTrainedConfig`]): + The model configuration. + device (`torch.device`): + The device to use for initialization of the inverse frequencies. + seq_len (`int`, *optional*): + The current sequence length. Unused for this type of RoPE. + Returns: + Tuple of (`torch.Tensor`, `float`), containing the inverse frequencies for the RoPE embeddings and the + post-processing scaling factor applied to the computed cos/sin (unused in this type of RoPE). + """ + base = config.rope_parameters["rope_theta"] + partial_rotary_factor = config.rope_parameters.get("partial_rotary_factor", 1.0) + head_dim = getattr(config, "head_dim", None) or config.hidden_size // config.num_attention_heads + dim = int(head_dim * partial_rotary_factor) + + attention_factor = 1.0 # Unused in this type of RoPE + + # Compute the inverse frequencies + inv_freq = 1.0 / ( + base ** (torch.arange(0, dim, 2, dtype=torch.int64).to(device=device, dtype=torch.float) / dim) + ) + return inv_freq, attention_factor + + @torch.no_grad() + @dynamic_rope_update # power user: used with advanced RoPE types (e.g. dynamic rope) + def forward(self, x, position_ids): + inv_freq_expanded = self.inv_freq[None, :, None].float().expand(position_ids.shape[0], -1, 1).to(x.device) + position_ids_expanded = position_ids[:, None, :].float() + + device_type = x.device.type if isinstance(x.device.type, str) and x.device.type != "mps" else "cpu" + with maybe_autocast(device_type=device_type, enabled=False): # Force float32 + freqs = (inv_freq_expanded.float() @ position_ids_expanded.float()).transpose(1, 2) + emb = torch.cat((freqs, freqs), dim=-1) + cos = emb.cos() * self.attention_scaling + sin = emb.sin() * self.attention_scaling + + return cos.to(dtype=x.dtype), sin.to(dtype=x.dtype) + + +def rotate_half(x): + """Rotates half the hidden dims of the input.""" + x1 = x[..., : x.shape[-1] // 2] + x2 = x[..., x.shape[-1] // 2 :] + return torch.cat((-x2, x1), dim=-1) + + +@use_kernel_func_from_hub("rotary_pos_emb") +def apply_rotary_pos_emb(q, k, cos, sin, unsqueeze_dim=1): + """Applies Rotary Position Embedding to the query and key tensors. + + Args: + q (`torch.Tensor`): The query tensor. + k (`torch.Tensor`): The key tensor. + cos (`torch.Tensor`): The cosine part of the rotary embedding. + sin (`torch.Tensor`): The sine part of the rotary embedding. + unsqueeze_dim (`int`, *optional*, defaults to 1): + The 'unsqueeze_dim' argument specifies the dimension along which to unsqueeze cos[position_ids] and + sin[position_ids] so that they can be properly broadcasted to the dimensions of q and k. For example, note + that cos[position_ids] and sin[position_ids] have the shape [batch_size, seq_len, head_dim]. Then, if q and + k have the shape [batch_size, heads, seq_len, head_dim], then setting unsqueeze_dim=1 makes + cos[position_ids] and sin[position_ids] broadcastable to the shapes of q and k. Similarly, if q and k have + the shape [batch_size, seq_len, heads, head_dim], then set unsqueeze_dim=2. + Returns: + `tuple(torch.Tensor)` comprising of the query and key tensors rotated using the Rotary Position Embedding. + """ + cos = cos.unsqueeze(unsqueeze_dim) + sin = sin.unsqueeze(unsqueeze_dim) + q_embed = (q * cos) + (rotate_half(q) * sin) + k_embed = (k * cos) + (rotate_half(k) * sin) + return q_embed, k_embed + + +def repeat_kv(hidden_states: torch.Tensor, n_rep: int) -> torch.Tensor: + """ + This is the equivalent of torch.repeat_interleave(x, dim=1, repeats=n_rep). The hidden states go from (batch, + num_key_value_heads, seqlen, head_dim) to (batch, num_attention_heads, seqlen, head_dim) + """ + batch, num_key_value_heads, slen, head_dim = hidden_states.shape + if n_rep == 1: + return hidden_states + hidden_states = hidden_states[:, :, None, :, :].expand(batch, num_key_value_heads, n_rep, slen, head_dim) + return hidden_states.reshape(batch, num_key_value_heads * n_rep, slen, head_dim) + + +def eager_attention_forward( + module: nn.Module, + query: torch.Tensor, + key: torch.Tensor, + value: torch.Tensor, + attention_mask: torch.Tensor | None, + scaling: float, + dropout: float = 0.0, + **kwargs: Unpack[TransformersKwargs], +): + key_states = repeat_kv(key, module.num_key_value_groups) + value_states = repeat_kv(value, module.num_key_value_groups) + + attn_weights = torch.matmul(query, key_states.transpose(2, 3)) * scaling + if attention_mask is not None: + attn_weights = attn_weights + attention_mask + + attn_weights = nn.functional.softmax(attn_weights, dim=-1, dtype=torch.float32).to(query.dtype) + attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training) + attn_output = torch.matmul(attn_weights, value_states) + attn_output = attn_output.transpose(1, 2).contiguous() + + return attn_output, attn_weights + + +@use_kernelized_func(apply_rotary_pos_emb) +class PhiAttention(nn.Module): + """Multi-headed attention from 'Attention Is All You Need' paper""" + + def __init__(self, config: PhiConfig, layer_idx: int): + super().__init__() + self.config = config + self.layer_idx = layer_idx + self.head_dim = getattr(config, "head_dim", config.hidden_size // config.num_attention_heads) + self.num_key_value_groups = config.num_attention_heads // config.num_key_value_heads + self.scaling = self.head_dim**-0.5 + self.attention_dropout = config.attention_dropout + self.is_causal = True + self.q_proj = nn.Linear(config.hidden_size, config.num_attention_heads * self.head_dim, bias=True) + self.k_proj = nn.Linear(config.hidden_size, config.num_key_value_heads * self.head_dim, bias=True) + self.v_proj = nn.Linear(config.hidden_size, config.num_key_value_heads * self.head_dim, bias=True) + self.dense = nn.Linear(config.num_attention_heads * self.head_dim, config.hidden_size, bias=True) + self.rotary_ndims = int(self.head_dim * config.rope_parameters["partial_rotary_factor"]) + self.qk_layernorm = config.qk_layernorm + if self.qk_layernorm: + self.q_layernorm = nn.LayerNorm( + config.hidden_size // config.num_attention_heads, eps=config.layer_norm_eps, elementwise_affine=True + ) + self.k_layernorm = nn.LayerNorm( + config.hidden_size // config.num_attention_heads, eps=config.layer_norm_eps, elementwise_affine=True + ) + + def forward( + self, + hidden_states: torch.Tensor, + position_embeddings: tuple[torch.Tensor, torch.Tensor], + attention_mask: torch.Tensor | None, + past_key_values: Cache | None = None, + cache_position: torch.LongTensor | None = None, + **kwargs, + ) -> tuple[torch.Tensor, torch.Tensor | None]: + input_shape = hidden_states.shape[:-1] + hidden_shape = (*input_shape, -1, self.head_dim) + + query_states = self.q_proj(hidden_states).view(hidden_shape).transpose(1, 2) + key_states = self.k_proj(hidden_states).view(hidden_shape).transpose(1, 2) + value_states = self.v_proj(hidden_states).view(hidden_shape).transpose(1, 2) + + if self.qk_layernorm: + query_states = self.q_layernorm(query_states) + key_states = self.k_layernorm(key_states) + + cos, sin = position_embeddings + # Partial rotary embedding + query_rot, query_pass = ( + query_states[..., : self.rotary_ndims], + query_states[..., self.rotary_ndims :], + ) + key_rot, key_pass = ( + key_states[..., : self.rotary_ndims], + key_states[..., self.rotary_ndims :], + ) + # [batch_size, seq_length, num_heads, head_dim // config.partial_rotary_factor] + query_rot, key_rot = apply_rotary_pos_emb(query_rot, key_rot, cos, sin) + + # [batch_size, seq_length, num_heads, head_dim] + query_states = torch.cat((query_rot, query_pass), dim=-1) + key_states = torch.cat((key_rot, key_pass), dim=-1) + + if past_key_values is not None: + # sin and cos are specific to RoPE models; cache_position needed for the static cache + cache_kwargs = {"sin": sin, "cos": cos, "cache_position": cache_position} + key_states, value_states = past_key_values.update(key_states, value_states, self.layer_idx, cache_kwargs) + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, eager_attention_forward + ) + + attn_output, attn_weights = attention_interface( + self, + query_states, + key_states, + value_states, + attention_mask, + dropout=0.0 if not self.training else self.attention_dropout, + scaling=self.scaling, + **kwargs, + ) + + attn_output = attn_output.reshape(*input_shape, -1).contiguous() + attn_output = self.dense(attn_output) + return attn_output, attn_weights + + +class PhiMLP(nn.Module): + def __init__(self, config): + super().__init__() + self.config = config + self.activation_fn = ACT2FN[config.hidden_act] + self.fc1 = nn.Linear(config.hidden_size, config.intermediate_size) + self.fc2 = nn.Linear(config.intermediate_size, config.hidden_size) + + def forward(self, hidden_states: torch.Tensor) -> torch.Tensor: + hidden_states = self.fc1(hidden_states) + hidden_states = self.activation_fn(hidden_states) + hidden_states = self.fc2(hidden_states) + return hidden_states + + +class PhiDecoderLayer(GradientCheckpointingLayer): + def __init__(self, config: PhiConfig, layer_idx: int): + super().__init__() + self.self_attn = PhiAttention(config, layer_idx=layer_idx) + self.mlp = PhiMLP(config) + self.input_layernorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps) + self.resid_dropout = nn.Dropout(config.resid_pdrop) + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.Tensor | None = None, + position_ids: torch.LongTensor | None = None, + past_key_values: Cache | None = None, + output_attentions: bool | None = False, + use_cache: bool | None = False, + cache_position: torch.LongTensor | None = None, + position_embeddings: tuple[torch.Tensor, torch.Tensor] | None = None, + **kwargs, + ) -> tuple[torch.FloatTensor, tuple[torch.FloatTensor, torch.FloatTensor] | None]: + residual = hidden_states + + hidden_states = self.input_layernorm(hidden_states) + + # Self Attention + attn_outputs, self_attn_weights = self.self_attn( + hidden_states=hidden_states, + attention_mask=attention_mask, + position_ids=position_ids, + past_key_values=past_key_values, + output_attentions=output_attentions, + use_cache=use_cache, + cache_position=cache_position, + position_embeddings=position_embeddings, + **kwargs, + ) + attn_outputs = self.resid_dropout(attn_outputs) + + feed_forward_hidden_states = self.resid_dropout(self.mlp(hidden_states)) + hidden_states = attn_outputs + feed_forward_hidden_states + residual + outputs = (hidden_states,) + + if output_attentions: + outputs += (self_attn_weights,) + + return outputs + + +@auto_docstring +class PhiPreTrainedModel(PreTrainedModel): + config: PhiConfig + base_model_prefix = "model" + supports_gradient_checkpointing = True + _no_split_modules = ["PhiDecoderLayer"] + _skip_keys_device_placement = ["past_key_values"] + _supports_flash_attn = True + _supports_sdpa = True + _supports_flex_attn = True + + _can_compile_fullgraph = True + _supports_attention_backend = True + _can_record_outputs = { + "hidden_states": PhiDecoderLayer, + "attentions": PhiAttention, + } + + +@auto_docstring +class PhiModel(PhiPreTrainedModel): + def __init__(self, config: PhiConfig): + super().__init__(config) + self.padding_idx = config.pad_token_id + self.vocab_size = config.vocab_size + + self.embed_tokens = nn.Embedding(config.vocab_size, config.hidden_size, self.padding_idx) + self.layers = nn.ModuleList( + [PhiDecoderLayer(config, layer_idx) for layer_idx in range(config.num_hidden_layers)] + ) + self.rotary_emb = PhiRotaryEmbedding(config=config) + self.gradient_checkpointing = False + self.embed_dropout = nn.Dropout(config.embd_pdrop) + self.final_layernorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps) + + # Initialize weights and apply final processing + self.post_init() + + @merge_with_config_defaults + @capture_outputs + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.Tensor | None = None, + position_ids: torch.LongTensor | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.FloatTensor | None = None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + cache_position: torch.LongTensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> BaseModelOutputWithPast: + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + use_cache = use_cache if use_cache is not None else self.config.use_cache + + if (input_ids is None) ^ (inputs_embeds is not None): + raise ValueError("You must specify exactly one of input_ids or inputs_embeds") + + if self.gradient_checkpointing and self.training and use_cache: + logger.warning_once( + "`use_cache=True` is incompatible with gradient checkpointing. Setting `use_cache=False`." + ) + use_cache = False + + if inputs_embeds is None: + inputs_embeds = self.embed_tokens(input_ids) + + if use_cache and past_key_values is None: + past_key_values = DynamicCache(config=self.config) + + if cache_position is None: + past_seen_tokens = past_key_values.get_seq_length() if past_key_values is not None else 0 + cache_position = torch.arange( + past_seen_tokens, past_seen_tokens + inputs_embeds.shape[1], device=inputs_embeds.device + ) + + if position_ids is None: + position_ids = cache_position.unsqueeze(0) + + causal_mask = create_causal_mask( + config=self.config, + inputs_embeds=inputs_embeds, + attention_mask=attention_mask, + cache_position=cache_position, + past_key_values=past_key_values, + position_ids=position_ids, + ) + + inputs_embeds = self.embed_dropout(inputs_embeds) # diff with Llama + hidden_states = inputs_embeds + position_embeddings = self.rotary_emb(hidden_states, position_ids=position_ids) + + # decoder layers + all_hidden_states = () if output_hidden_states else None + all_self_attns = () if output_attentions else None + + for decoder_layer in self.layers[: self.config.num_hidden_layers]: + if output_hidden_states: + all_hidden_states += (hidden_states,) + + layer_outputs = decoder_layer( + hidden_states, + attention_mask=causal_mask, + position_ids=position_ids, + past_key_values=past_key_values, + output_attentions=output_attentions, + use_cache=use_cache, + cache_position=cache_position, + position_embeddings=position_embeddings, + **kwargs, + ) + + hidden_states = layer_outputs[0] + + if output_attentions: + all_self_attns += (layer_outputs[1],) + + hidden_states = self.final_layernorm(hidden_states) # diff with Llama + + # add hidden states from the last decoder layer + if output_hidden_states: + all_hidden_states += (hidden_states,) + + return BaseModelOutputWithPast( + last_hidden_state=hidden_states, + past_key_values=past_key_values if use_cache else None, + hidden_states=all_hidden_states, + attentions=all_self_attns, + ) + + +@auto_docstring +class PhiForCausalLM(PhiPreTrainedModel, GenerationMixin): + _tied_weights_keys = {"lm_head.weight": "model.embed_tokens.weight"} + _tp_plan = {"lm_head": "colwise_gather_output"} + _pp_plan = {"lm_head": (["hidden_states"], ["logits"])} + + def __init__(self, config): + super().__init__(config) + self.model = PhiModel(config) + self.vocab_size = config.vocab_size + self.lm_head = nn.Linear(config.hidden_size, config.vocab_size, bias=True) + + # Initialize weights and apply final processing + self.post_init() + + @can_return_tuple + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.Tensor | None = None, + position_ids: torch.LongTensor | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.FloatTensor | None = None, + labels: torch.LongTensor | None = None, + use_cache: bool | None = None, + cache_position: torch.LongTensor | None = None, + logits_to_keep: int | torch.Tensor = 0, + **kwargs: Unpack[TransformersKwargs], + ) -> CausalLMOutputWithPast: + r""" + Example: + + ```python + >>> from transformers import AutoTokenizer, PhiForCausalLM + + >>> model = PhiForCausalLM.from_pretrained("meta-phi/Phi-2-7b-hf") + >>> tokenizer = AutoTokenizer.from_pretrained("meta-phi/Phi-2-7b-hf") + + >>> prompt = "Hey, are you conscious? Can you talk to me?" + >>> inputs = tokenizer(prompt, return_tensors="pt") + + >>> # Generate + >>> generate_ids = model.generate(inputs.input_ids, max_length=30) + >>> tokenizer.batch_decode(generate_ids, skip_special_tokens=True, clean_up_tokenization_spaces=False)[0] + "Hey, are you conscious? Can you talk to me?\nI'm not conscious, but I can talk to you." + ```""" + outputs: BaseModelOutputWithPast = self.model( + input_ids=input_ids, + attention_mask=attention_mask, + position_ids=position_ids, + past_key_values=past_key_values, + inputs_embeds=inputs_embeds, + use_cache=use_cache, + cache_position=cache_position, + **kwargs, + ) + + hidden_states = outputs.last_hidden_state + # Only compute necessary logits, and do not upcast them to float if we are not computing the loss + slice_indices = slice(-logits_to_keep, None) if isinstance(logits_to_keep, int) else logits_to_keep + logits = self.lm_head(hidden_states[:, slice_indices, :]) + + loss = None + if labels is not None: + loss = self.loss_function(logits=logits, labels=labels, vocab_size=self.config.vocab_size, **kwargs) + + return CausalLMOutputWithPast( + loss=loss, + logits=logits, + past_key_values=outputs.past_key_values, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + ) + + +class PhiForSequenceClassification(GenericForSequenceClassification, PhiPreTrainedModel): + pass + + +class PhiForTokenClassification(GenericForTokenClassification, PhiPreTrainedModel): + pass + + +__all__ = [ + "PhiPreTrainedModel", + "PhiModel", + "PhiForCausalLM", + "PhiForSequenceClassification", + "PhiForTokenClassification", +] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/phi/modular_phi.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/phi/modular_phi.py new file mode 100644 index 0000000000000000000000000000000000000000..7c3a33f00243b1a1157a22dc4058cda2c84e5d52 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/phi/modular_phi.py @@ -0,0 +1,327 @@ +from collections.abc import Callable +from typing import Optional + +import torch +import torch.nn as nn + +from ...cache_utils import Cache, DynamicCache +from ...masking_utils import create_causal_mask +from ...modeling_layers import GradientCheckpointingLayer +from ...modeling_outputs import ( + BaseModelOutputWithPast, +) +from ...modeling_utils import ALL_ATTENTION_FUNCTIONS +from ...processing_utils import Unpack +from ...utils import TransformersKwargs, logging +from ..clip.modeling_clip import CLIPMLP +from ..llama.modeling_llama import ( + LlamaAttention, + LlamaForCausalLM, + LlamaForSequenceClassification, + LlamaForTokenClassification, + LlamaModel, + LlamaRotaryEmbedding, + apply_rotary_pos_emb, + eager_attention_forward, # copied from Llama +) +from .configuration_phi import PhiConfig + + +logger = logging.get_logger(__name__) + +_CHECKPOINT_FOR_DOC = "microsoft/phi-1" +_CONFIG_FOR_DOC = "PhiConfig" + + +class PhiRotaryEmbedding(LlamaRotaryEmbedding): + @staticmethod + def compute_default_rope_parameters( + config: PhiConfig | None = None, + device: Optional["torch.device"] = None, + seq_len: int | None = None, + ) -> tuple["torch.Tensor", float]: + """ + Computes the inverse frequencies according to the original RoPE implementation + Args: + config ([`~transformers.PreTrainedConfig`]): + The model configuration. + device (`torch.device`): + The device to use for initialization of the inverse frequencies. + seq_len (`int`, *optional*): + The current sequence length. Unused for this type of RoPE. + Returns: + Tuple of (`torch.Tensor`, `float`), containing the inverse frequencies for the RoPE embeddings and the + post-processing scaling factor applied to the computed cos/sin (unused in this type of RoPE). + """ + base = config.rope_parameters["rope_theta"] + partial_rotary_factor = config.rope_parameters.get("partial_rotary_factor", 1.0) + head_dim = getattr(config, "head_dim", None) or config.hidden_size // config.num_attention_heads + dim = int(head_dim * partial_rotary_factor) + + attention_factor = 1.0 # Unused in this type of RoPE + + # Compute the inverse frequencies + inv_freq = 1.0 / ( + base ** (torch.arange(0, dim, 2, dtype=torch.int64).to(device=device, dtype=torch.float) / dim) + ) + return inv_freq, attention_factor + + +class PhiAttention(LlamaAttention): + def __init__(self, config: PhiConfig, layer_idx: int): + super().__init__(config, layer_idx) + self.q_proj = nn.Linear(config.hidden_size, config.num_attention_heads * self.head_dim, bias=True) + self.k_proj = nn.Linear(config.hidden_size, config.num_key_value_heads * self.head_dim, bias=True) + self.v_proj = nn.Linear(config.hidden_size, config.num_key_value_heads * self.head_dim, bias=True) + self.dense = nn.Linear(config.num_attention_heads * self.head_dim, config.hidden_size, bias=True) + del self.o_proj + self.rotary_ndims = int(self.head_dim * config.rope_parameters["partial_rotary_factor"]) + self.qk_layernorm = config.qk_layernorm + if self.qk_layernorm: + self.q_layernorm = nn.LayerNorm( + config.hidden_size // config.num_attention_heads, eps=config.layer_norm_eps, elementwise_affine=True + ) + self.k_layernorm = nn.LayerNorm( + config.hidden_size // config.num_attention_heads, eps=config.layer_norm_eps, elementwise_affine=True + ) + + def forward( + self, + hidden_states: torch.Tensor, + position_embeddings: tuple[torch.Tensor, torch.Tensor], + attention_mask: torch.Tensor | None, + past_key_values: Cache | None = None, + cache_position: torch.LongTensor | None = None, + **kwargs, + ) -> tuple[torch.Tensor, torch.Tensor | None]: + input_shape = hidden_states.shape[:-1] + hidden_shape = (*input_shape, -1, self.head_dim) + + query_states = self.q_proj(hidden_states).view(hidden_shape).transpose(1, 2) + key_states = self.k_proj(hidden_states).view(hidden_shape).transpose(1, 2) + value_states = self.v_proj(hidden_states).view(hidden_shape).transpose(1, 2) + + if self.qk_layernorm: + query_states = self.q_layernorm(query_states) + key_states = self.k_layernorm(key_states) + + cos, sin = position_embeddings + # Partial rotary embedding + query_rot, query_pass = ( + query_states[..., : self.rotary_ndims], + query_states[..., self.rotary_ndims :], + ) + key_rot, key_pass = ( + key_states[..., : self.rotary_ndims], + key_states[..., self.rotary_ndims :], + ) + # [batch_size, seq_length, num_heads, head_dim // config.partial_rotary_factor] + query_rot, key_rot = apply_rotary_pos_emb(query_rot, key_rot, cos, sin) + + # [batch_size, seq_length, num_heads, head_dim] + query_states = torch.cat((query_rot, query_pass), dim=-1) + key_states = torch.cat((key_rot, key_pass), dim=-1) + + if past_key_values is not None: + # sin and cos are specific to RoPE models; cache_position needed for the static cache + cache_kwargs = {"sin": sin, "cos": cos, "cache_position": cache_position} + key_states, value_states = past_key_values.update(key_states, value_states, self.layer_idx, cache_kwargs) + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, eager_attention_forward + ) + + attn_output, attn_weights = attention_interface( + self, + query_states, + key_states, + value_states, + attention_mask, + dropout=0.0 if not self.training else self.attention_dropout, + scaling=self.scaling, + **kwargs, + ) + + attn_output = attn_output.reshape(*input_shape, -1).contiguous() + attn_output = self.dense(attn_output) + return attn_output, attn_weights + + +class PhiMLP(CLIPMLP): + pass + + +class PhiDecoderLayer(GradientCheckpointingLayer): + def __init__(self, config: PhiConfig, layer_idx: int): + super().__init__() + self.self_attn = PhiAttention(config, layer_idx=layer_idx) + self.mlp = PhiMLP(config) + self.input_layernorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps) + self.resid_dropout = nn.Dropout(config.resid_pdrop) + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.Tensor | None = None, + position_ids: torch.LongTensor | None = None, + past_key_values: Cache | None = None, + output_attentions: bool | None = False, + use_cache: bool | None = False, + cache_position: torch.LongTensor | None = None, + position_embeddings: tuple[torch.Tensor, torch.Tensor] | None = None, + **kwargs, + ) -> tuple[torch.FloatTensor, tuple[torch.FloatTensor, torch.FloatTensor] | None]: + residual = hidden_states + + hidden_states = self.input_layernorm(hidden_states) + + # Self Attention + attn_outputs, self_attn_weights = self.self_attn( + hidden_states=hidden_states, + attention_mask=attention_mask, + position_ids=position_ids, + past_key_values=past_key_values, + output_attentions=output_attentions, + use_cache=use_cache, + cache_position=cache_position, + position_embeddings=position_embeddings, + **kwargs, + ) + attn_outputs = self.resid_dropout(attn_outputs) + + feed_forward_hidden_states = self.resid_dropout(self.mlp(hidden_states)) + hidden_states = attn_outputs + feed_forward_hidden_states + residual + outputs = (hidden_states,) + + if output_attentions: + outputs += (self_attn_weights,) + + return outputs + + +class PhiModel(LlamaModel): + def __init__(self, config: PhiConfig): + super().__init__(config) + self.layers = nn.ModuleList( + [PhiDecoderLayer(config, layer_idx) for layer_idx in range(config.num_hidden_layers)] + ) + self.embed_dropout = nn.Dropout(config.embd_pdrop) + self.final_layernorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps) + del self.norm + + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.Tensor | None = None, + position_ids: torch.LongTensor | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.FloatTensor | None = None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + cache_position: torch.LongTensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> BaseModelOutputWithPast: + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + use_cache = use_cache if use_cache is not None else self.config.use_cache + + if (input_ids is None) ^ (inputs_embeds is not None): + raise ValueError("You must specify exactly one of input_ids or inputs_embeds") + + if self.gradient_checkpointing and self.training and use_cache: + logger.warning_once( + "`use_cache=True` is incompatible with gradient checkpointing. Setting `use_cache=False`." + ) + use_cache = False + + if inputs_embeds is None: + inputs_embeds = self.embed_tokens(input_ids) + + if use_cache and past_key_values is None: + past_key_values = DynamicCache(config=self.config) + + if cache_position is None: + past_seen_tokens = past_key_values.get_seq_length() if past_key_values is not None else 0 + cache_position = torch.arange( + past_seen_tokens, past_seen_tokens + inputs_embeds.shape[1], device=inputs_embeds.device + ) + + if position_ids is None: + position_ids = cache_position.unsqueeze(0) + + causal_mask = create_causal_mask( + config=self.config, + inputs_embeds=inputs_embeds, + attention_mask=attention_mask, + cache_position=cache_position, + past_key_values=past_key_values, + position_ids=position_ids, + ) + + inputs_embeds = self.embed_dropout(inputs_embeds) # diff with Llama + hidden_states = inputs_embeds + position_embeddings = self.rotary_emb(hidden_states, position_ids=position_ids) + + # decoder layers + all_hidden_states = () if output_hidden_states else None + all_self_attns = () if output_attentions else None + + for decoder_layer in self.layers[: self.config.num_hidden_layers]: + if output_hidden_states: + all_hidden_states += (hidden_states,) + + layer_outputs = decoder_layer( + hidden_states, + attention_mask=causal_mask, + position_ids=position_ids, + past_key_values=past_key_values, + output_attentions=output_attentions, + use_cache=use_cache, + cache_position=cache_position, + position_embeddings=position_embeddings, + **kwargs, + ) + + hidden_states = layer_outputs[0] + + if output_attentions: + all_self_attns += (layer_outputs[1],) + + hidden_states = self.final_layernorm(hidden_states) # diff with Llama + + # add hidden states from the last decoder layer + if output_hidden_states: + all_hidden_states += (hidden_states,) + + return BaseModelOutputWithPast( + last_hidden_state=hidden_states, + past_key_values=past_key_values if use_cache else None, + hidden_states=all_hidden_states, + attentions=all_self_attns, + ) + + +class PhiForCausalLM(LlamaForCausalLM): + def __init__(self, config): + super().__init__(config) + self.lm_head = nn.Linear(config.hidden_size, config.vocab_size, bias=True) + + +class PhiForSequenceClassification(LlamaForSequenceClassification): + pass + + +class PhiForTokenClassification(LlamaForTokenClassification): + pass + + +__all__ = [ + "PhiPreTrainedModel", # noqa: F822 + "PhiModel", + "PhiForCausalLM", + "PhiForSequenceClassification", + "PhiForTokenClassification", +] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/phi3/__init__.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/phi3/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..0cb1e7a9cd04fb32cb8eb29516d95c0fc8e9d108 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/phi3/__init__.py @@ -0,0 +1,27 @@ +# Copyright 2024 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from typing import TYPE_CHECKING + +from ...utils import _LazyModule +from ...utils.import_utils import define_import_structure + + +if TYPE_CHECKING: + from .configuration_phi3 import * + from .modeling_phi3 import * +else: + import sys + + _file = globals()["__file__"] + sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__) diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/phi3/configuration_phi3.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/phi3/configuration_phi3.py new file mode 100644 index 0000000000000000000000000000000000000000..0c7f3ff74e73743e7a366c2a4601cce8b1b4a237 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/phi3/configuration_phi3.py @@ -0,0 +1,237 @@ +# Copyright 2024 Microsoft and the HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +"""Phi-3 model configuration""" + +from ...configuration_utils import PreTrainedConfig +from ...modeling_rope_utils import RopeParameters +from ...utils import logging + + +logger = logging.get_logger(__name__) + + +class Phi3Config(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`Phi3Model`]. It is used to instantiate a Phi-3 + model according to the specified arguments, defining the model architecture. Instantiating a configuration with the + defaults will yield a similar configuration to that of the + [microsoft/Phi-3-mini-4k-instruct](https://huggingface.co/microsoft/Phi-3-mini-4k-instruct). + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + vocab_size (`int`, *optional*, defaults to 32064): + Vocabulary size of the Phi-3 model. Defines the number of different tokens that can be represented by the + `inputs_ids` passed when calling [`Phi3Model`]. + hidden_size (`int`, *optional*, defaults to 3072): + Dimension of the hidden representations. + intermediate_size (`int`, *optional*, defaults to 8192): + Dimension of the MLP representations. + num_hidden_layers (`int`, *optional*, defaults to 32): + Number of hidden layers in the Transformer decoder. + num_attention_heads (`int`, *optional*, defaults to 32): + Number of attention heads for each attention layer in the Transformer decoder. + num_key_value_heads (`int`, *optional*): + This is the number of key_value heads that should be used to implement Grouped Query Attention. If + `num_key_value_heads=num_attention_heads`, the model will use Multi Head Attention (MHA), if + `num_key_value_heads=1` the model will use Multi Query Attention (MQA) otherwise GQA is used. When + converting a multi-head checkpoint to a GQA checkpoint, each group key and value head should be constructed + by meanpooling all the original heads within that group. For more details, check out [this + paper](https://huggingface.co/papers/2305.13245). If it is not specified, will default to + `num_attention_heads`. + resid_pdrop (`float`, *optional*, defaults to 0.0): + Dropout probability for mlp outputs. + embd_pdrop (`int`, *optional*, defaults to 0.0): + The dropout ratio for the embeddings. + attention_dropout (`float`, *optional*, defaults to 0.0): + The dropout ratio after computing the attention scores. + hidden_act (`str` or `function`, *optional*, defaults to `"silu"`): + The non-linear activation function (function or string) in the decoder. + max_position_embeddings (`int`, *optional*, defaults to 4096): + The maximum sequence length that this model might ever be used with. + original_max_position_embeddings (`int`, *optional*, defaults to 4096): + The maximum sequence length that this model was trained with. This is used to determine the size of the + original RoPE embeddings when using long scaling. + initializer_range (`float`, *optional*, defaults to 0.02): + The standard deviation of the truncated_normal_initializer for initializing all weight matrices. + rms_norm_eps (`float`, *optional*, defaults to 1e-05): + The epsilon value used for the RMSNorm. + use_cache (`bool`, *optional*, defaults to `True`): + Whether or not the model should return the last key/values attentions (not used by all models). Only + relevant if `config.is_decoder=True`. Whether to tie weight embeddings or not. + tie_word_embeddings (`bool`, *optional*, defaults to `False`): + Whether to tie weight embeddings + rope_parameters (`RopeParameters`, *optional*): + Dictionary containing the configuration parameters for the RoPE embeddings. The dictionary should contain + a value for `rope_theta` and optionally parameters used for scaling in case you want to use RoPE + with longer `max_position_embeddings`. + bos_token_id (`int`, *optional*, defaults to 1): + The id of the "beginning-of-sequence" token. + eos_token_id (`int`, *optional*, defaults to 32000): + The id of the "end-of-sequence" token. + pad_token_id (`int`, *optional*, defaults to 32000): + The id of the padding token. + sliding_window (`int`, *optional*): + Sliding window attention window size. If `None`, no sliding window is applied. + + Example: + + ```python + >>> from transformers import Phi3Model, Phi3Config + + >>> # Initializing a Phi-3 style configuration + >>> configuration = Phi3Config.from_pretrained("microsoft/Phi-3-mini-4k-instruct") + + >>> # Initializing a model from the configuration + >>> model = Phi3Model(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "phi3" + keys_to_ignore_at_inference = ["past_key_values"] + base_model_tp_plan = { + "layers.*.self_attn.qkv_proj": "colwise_gather_output", # we need to replicate here due to the slicing of qkv + "layers.*.self_attn.o_proj": "rowwise_split_input", # input is replicated due to the slicing of qkv + "layers.*.mlp.gate_up_proj": "colwise_gather_output", # we need to replicate here due to the `chunk` operation + "layers.*.mlp.down_proj": "rowwise_split_input", # input is replicated due to the `chunk` operation + } + base_model_pp_plan = { + "embed_tokens": (["input_ids"], ["inputs_embeds"]), + "layers": (["hidden_states", "attention_mask"], ["hidden_states"]), + "norm": (["hidden_states"], ["hidden_states"]), + } + + def __init__( + self, + vocab_size: int | None = 32064, + hidden_size: int | None = 3072, + intermediate_size: int | None = 8192, + num_hidden_layers: int | None = 32, + num_attention_heads: int | None = 32, + num_key_value_heads: int | None = None, + resid_pdrop: float | None = 0.0, + embd_pdrop: float | None = 0.0, + attention_dropout: float | None = 0.0, + hidden_act: str | None = "silu", + max_position_embeddings: int | None = 4096, + original_max_position_embeddings: int | None = 4096, + initializer_range: float | None = 0.02, + rms_norm_eps: int | None = 1e-5, + use_cache: bool | None = True, + tie_word_embeddings: bool | None = False, + rope_parameters: RopeParameters | dict[str, RopeParameters] | None = None, + bos_token_id: int | None = 1, + eos_token_id: int | None = 32000, + pad_token_id: int | None = 32000, + sliding_window: int | None = None, + **kwargs, + ): + self.vocab_size = vocab_size + self.hidden_size = hidden_size + self.intermediate_size = intermediate_size + self.num_hidden_layers = num_hidden_layers + self.num_attention_heads = num_attention_heads + + if num_key_value_heads is None: + num_key_value_heads = num_attention_heads + + self.num_key_value_heads = num_key_value_heads + self.resid_pdrop = resid_pdrop + self.embd_pdrop = embd_pdrop + self.attention_dropout = attention_dropout + self.hidden_act = hidden_act + self.max_position_embeddings = max_position_embeddings + self.original_max_position_embeddings = original_max_position_embeddings + self.initializer_range = initializer_range + self.rms_norm_eps = rms_norm_eps + self.use_cache = use_cache + self.rope_parameters = rope_parameters + kwargs.setdefault("partial_rotary_factor", 1.0) # assign default for BC + self.sliding_window = sliding_window + + self.bos_token_id = bos_token_id + self.eos_token_id = eos_token_id + self.pad_token_id = pad_token_id + self.tie_word_embeddings = tie_word_embeddings + super().__init__(**kwargs) + + def convert_rope_params_to_dict( + self, default_theta: int | float = 10_000.0, ignore_keys: set | None = None, **kwargs + ): + rope_scaling = kwargs.pop("rope_scaling", None) + self.rope_parameters = rope_scaling or self.rope_parameters + self.rope_parameters = self.rope_parameters if self.rope_parameters is not None else {} + + # Standardize and validate the correctness of rotary position embeddings parameters + self.rope_parameters.setdefault("rope_theta", kwargs.pop("rope_theta", default_theta)) + self.rope_parameters.setdefault("partial_rotary_factor", kwargs["partial_rotary_factor"]) + self.standardize_rope_params() + + # For backward compatibility if previous version used "su" or "yarn" + rope_parameters_type = self.rope_parameters.get("rope_type", None) + if rope_parameters_type is not None and rope_parameters_type in ["su", "yarn"]: + self.rope_parameters["rope_type"] = "longrope" + self.validate_rope(ignore_keys=ignore_keys) + return kwargs + + def validate_rope(self, ignore_keys: set | None = None): + """ + Validate the `rope_parameters` configuration. + """ + super().validate_rope(ignore_keys=ignore_keys) + + # Run Phi3 specific validation + if not isinstance(self.rope_parameters, dict): + raise ValueError(f"`rope_parameters` must be a dictionary but got {self.rope_parameters}") + rope_parameters_type = self.rope_parameters.get("rope_type", None) + rope_parameters_short_factor = self.rope_parameters.get("short_factor", None) + rope_parameters_long_factor = self.rope_parameters.get("long_factor", None) + rotary_ndims = int( + self.hidden_size // self.num_attention_heads * self.rope_parameters["partial_rotary_factor"] + ) + if rope_parameters_type not in ["default", "longrope"]: + raise ValueError(f"`rope_parameters`'s type field must be one of ['longrope'], got {rope_parameters_type}") + + if rope_parameters_short_factor is not None: + if not ( + isinstance(rope_parameters_short_factor, list) + and all(isinstance(x, (int, float)) for x in rope_parameters_short_factor) + ): + raise ValueError( + f"`rope_parameters`'s short_factor field must be a list of numbers, got {rope_parameters_short_factor}" + ) + if not len(rope_parameters_short_factor) == rotary_ndims // 2: + raise ValueError( + f"`rope_parameters`'s short_factor field must have length {rotary_ndims // 2}, got {len(rope_parameters_short_factor)}" + ) + + if rope_parameters_long_factor is not None: + if not ( + isinstance(rope_parameters_long_factor, list) + and all(isinstance(x, (int, float)) for x in rope_parameters_long_factor) + ): + raise ValueError( + f"`rope_parameters`'s long_factor field must be a list of numbers, got {rope_parameters_long_factor}" + ) + if not len(rope_parameters_long_factor) == rotary_ndims // 2: + raise ValueError( + f"`rope_parameters`'s long_factor field must have length {rotary_ndims // 2}, got {len(rope_parameters_long_factor)}" + ) + + +__all__ = ["Phi3Config"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/phi3/modeling_phi3.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/phi3/modeling_phi3.py new file mode 100644 index 0000000000000000000000000000000000000000..3e0bdef972cab0b7882bc398cfea46dbc2f00db4 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/phi3/modeling_phi3.py @@ -0,0 +1,573 @@ +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# This file was automatically generated from src/transformers/models/phi3/modular_phi3.py. +# Do NOT edit this file manually as any edits will be overwritten by the generation of +# the file from the modular. If any change should be done, please apply the change to the +# modular_phi3.py file directly. One of our CI enforces this. +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# Copyright 2024 Microsoft and the HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + + +from collections.abc import Callable +from typing import Optional + +import torch +from torch import nn + +from ...activations import ACT2FN +from ...cache_utils import Cache, DynamicCache +from ...generation import GenerationMixin +from ...integrations import use_kernel_forward_from_hub +from ...masking_utils import create_causal_mask, create_sliding_window_causal_mask +from ...modeling_flash_attention_utils import FlashAttentionKwargs +from ...modeling_layers import ( + GenericForSequenceClassification, + GenericForTokenClassification, + GradientCheckpointingLayer, +) +from ...modeling_outputs import BaseModelOutputWithPast, CausalLMOutputWithPast +from ...modeling_rope_utils import ROPE_INIT_FUNCTIONS, dynamic_rope_update +from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel +from ...processing_utils import Unpack +from ...utils import TransformersKwargs, auto_docstring, can_return_tuple +from ...utils.generic import maybe_autocast, merge_with_config_defaults +from ...utils.output_capturing import capture_outputs +from .configuration_phi3 import Phi3Config + + +class Phi3MLP(nn.Module): + def __init__(self, config): + super().__init__() + + self.config = config + self.gate_up_proj = nn.Linear(config.hidden_size, 2 * config.intermediate_size, bias=False) + self.down_proj = nn.Linear(config.intermediate_size, config.hidden_size, bias=False) + self.activation_fn = ACT2FN[config.hidden_act] + + def forward(self, hidden_states: torch.FloatTensor) -> torch.FloatTensor: + up_states = self.gate_up_proj(hidden_states) + + gate, up_states = up_states.chunk(2, dim=-1) + up_states = up_states * self.activation_fn(gate) + + return self.down_proj(up_states) + + +class Phi3RotaryEmbedding(nn.Module): + inv_freq: torch.Tensor # fix linting for `register_buffer` + + def __init__(self, config: Phi3Config, device=None): + super().__init__() + self.max_seq_len_cached = config.max_position_embeddings + self.original_max_seq_len = config.max_position_embeddings + + self.config = config + + self.rope_type = self.config.rope_parameters["rope_type"] + rope_init_fn: Callable = self.compute_default_rope_parameters + if self.rope_type != "default": + rope_init_fn = ROPE_INIT_FUNCTIONS[self.rope_type] + inv_freq, self.attention_scaling = rope_init_fn(self.config, device) + + self.register_buffer("inv_freq", inv_freq, persistent=False) + self.register_buffer("original_inv_freq", inv_freq.clone(), persistent=False) + + @staticmethod + def compute_default_rope_parameters( + config: Phi3Config | None = None, + device: Optional["torch.device"] = None, + seq_len: int | None = None, + ) -> tuple["torch.Tensor", float]: + """ + Computes the inverse frequencies according to the original RoPE implementation + Args: + config ([`~transformers.PreTrainedConfig`]): + The model configuration. + device (`torch.device`): + The device to use for initialization of the inverse frequencies. + seq_len (`int`, *optional*): + The current sequence length. Unused for this type of RoPE. + Returns: + Tuple of (`torch.Tensor`, `float`), containing the inverse frequencies for the RoPE embeddings and the + post-processing scaling factor applied to the computed cos/sin (unused in this type of RoPE). + """ + base = config.rope_parameters["rope_theta"] + partial_rotary_factor = config.rope_parameters.get("partial_rotary_factor", 1.0) + head_dim = getattr(config, "head_dim", None) or config.hidden_size // config.num_attention_heads + dim = int(head_dim * partial_rotary_factor) + + attention_factor = 1.0 # Unused in this type of RoPE + + # Compute the inverse frequencies + inv_freq = 1.0 / ( + base ** (torch.arange(0, dim, 2, dtype=torch.int64).to(device=device, dtype=torch.float) / dim) + ) + return inv_freq, attention_factor + + @torch.no_grad() + @dynamic_rope_update # power user: used with advanced RoPE types (e.g. dynamic rope) + def forward(self, x, position_ids): + inv_freq_expanded = self.inv_freq[None, :, None].float().expand(position_ids.shape[0], -1, 1).to(x.device) + position_ids_expanded = position_ids[:, None, :].float() + + device_type = x.device.type if isinstance(x.device.type, str) and x.device.type != "mps" else "cpu" + with maybe_autocast(device_type=device_type, enabled=False): # Force float32 + freqs = (inv_freq_expanded.float() @ position_ids_expanded.float()).transpose(1, 2) + emb = torch.cat((freqs, freqs), dim=-1) + cos = emb.cos() * self.attention_scaling + sin = emb.sin() * self.attention_scaling + + return cos.to(dtype=x.dtype), sin.to(dtype=x.dtype) + + +def rotate_half(x): + """Rotates half the hidden dims of the input.""" + x1 = x[..., : x.shape[-1] // 2] + x2 = x[..., x.shape[-1] // 2 :] + return torch.cat((-x2, x1), dim=-1) + + +def repeat_kv(hidden_states: torch.Tensor, n_rep: int) -> torch.Tensor: + """ + This is the equivalent of torch.repeat_interleave(x, dim=1, repeats=n_rep). The hidden states go from (batch, + num_key_value_heads, seqlen, head_dim) to (batch, num_attention_heads, seqlen, head_dim) + """ + batch, num_key_value_heads, slen, head_dim = hidden_states.shape + if n_rep == 1: + return hidden_states + hidden_states = hidden_states[:, :, None, :, :].expand(batch, num_key_value_heads, n_rep, slen, head_dim) + return hidden_states.reshape(batch, num_key_value_heads * n_rep, slen, head_dim) + + +def eager_attention_forward( + module: nn.Module, + query: torch.Tensor, + key: torch.Tensor, + value: torch.Tensor, + attention_mask: torch.Tensor | None, + scaling: float, + dropout: float = 0.0, + **kwargs: Unpack[TransformersKwargs], +): + key_states = repeat_kv(key, module.num_key_value_groups) + value_states = repeat_kv(value, module.num_key_value_groups) + + attn_weights = torch.matmul(query, key_states.transpose(2, 3)) * scaling + if attention_mask is not None: + attn_weights = attn_weights + attention_mask + + attn_weights = nn.functional.softmax(attn_weights, dim=-1, dtype=torch.float32).to(query.dtype) + attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training) + attn_output = torch.matmul(attn_weights, value_states) + attn_output = attn_output.transpose(1, 2).contiguous() + + return attn_output, attn_weights + + +def apply_rotary_pos_emb(q, k, cos, sin, unsqueeze_dim=1): + """Applies Rotary Position Embedding to the query and key tensors. + + Args: + q (`torch.Tensor`): The query tensor. + k (`torch.Tensor`): The key tensor. + cos (`torch.Tensor`): The cosine part of the rotary embedding. + sin (`torch.Tensor`): The sine part of the rotary embedding. + unsqueeze_dim (`int`, *optional*, defaults to 1): + The 'unsqueeze_dim' argument specifies the dimension along which to unsqueeze cos[position_ids] and + sin[position_ids] so that they can be properly broadcasted to the dimensions of q and k. For example, note + that cos[position_ids] and sin[position_ids] have the shape [batch_size, seq_len, head_dim]. Then, if q and + k have the shape [batch_size, heads, seq_len, head_dim], then setting unsqueeze_dim=1 makes + cos[position_ids] and sin[position_ids] broadcastable to the shapes of q and k. Similarly, if q and k have + the shape [batch_size, seq_len, heads, head_dim], then set unsqueeze_dim=2. + Returns: + `tuple(torch.Tensor)` comprising of the query and key tensors rotated using the Rotary Position Embedding. + """ + cos = cos.unsqueeze(unsqueeze_dim) + sin = sin.unsqueeze(unsqueeze_dim) + + rotary_dim = cos.shape[-1] + q_rot, q_pass = q[..., :rotary_dim], q[..., rotary_dim:] + k_rot, k_pass = k[..., :rotary_dim], k[..., rotary_dim:] + + q_embed = torch.cat([(q_rot * cos) + (rotate_half(q_rot) * sin), q_pass], dim=-1) + k_embed = torch.cat([(k_rot * cos) + (rotate_half(k_rot) * sin), k_pass], dim=-1) + return q_embed, k_embed + + +class Phi3Attention(nn.Module): + """Multi-headed attention from 'Attention Is All You Need' paper""" + + def __init__(self, config: Phi3Config, layer_idx: int | None = None): + super().__init__() + self.config = config + self.layer_idx = layer_idx + self.head_dim = getattr(config, "head_dim", config.hidden_size // config.num_attention_heads) + self.num_key_value_groups = config.num_attention_heads // config.num_key_value_heads + self.num_key_value_heads = config.num_key_value_heads + self.scaling = self.head_dim**-0.5 + self.attention_dropout = config.attention_dropout + self.is_causal = True + + op_size = config.num_attention_heads * self.head_dim + 2 * (config.num_key_value_heads * self.head_dim) + self.o_proj = nn.Linear(config.num_attention_heads * self.head_dim, config.hidden_size, bias=False) + self.qkv_proj = nn.Linear(config.hidden_size, op_size, bias=False) + + def forward( + self, + hidden_states: torch.Tensor, + position_embeddings: tuple[torch.Tensor, torch.Tensor], + attention_mask: torch.Tensor | None, + past_key_values: Cache | None = None, + cache_position: torch.LongTensor | None = None, + **kwargs: Unpack[FlashAttentionKwargs], + ) -> tuple[torch.Tensor, torch.Tensor | None, tuple[torch.Tensor] | None]: + input_shape = hidden_states.shape[:-1] + hidden_shape = (*input_shape, -1, self.head_dim) + + qkv = self.qkv_proj(hidden_states) + query_pos = self.config.num_attention_heads * self.head_dim + query_states = qkv[..., :query_pos] + key_states = qkv[..., query_pos : query_pos + self.num_key_value_heads * self.head_dim] + value_states = qkv[..., query_pos + self.num_key_value_heads * self.head_dim :] + + query_states = query_states.view(hidden_shape).transpose(1, 2) + key_states = key_states.view(hidden_shape).transpose(1, 2) + value_states = value_states.view(hidden_shape).transpose(1, 2) + + cos, sin = position_embeddings + query_states, key_states = apply_rotary_pos_emb(query_states, key_states, cos, sin) + + if past_key_values is not None: + # sin and cos are specific to RoPE models; cache_position needed for the static cache + cache_kwargs = {"sin": sin, "cos": cos, "cache_position": cache_position} + key_states, value_states = past_key_values.update(key_states, value_states, self.layer_idx, cache_kwargs) + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, eager_attention_forward + ) + + attn_output, attn_weights = attention_interface( + self, + query_states, + key_states, + value_states, + attention_mask, + dropout=0.0 if not self.training else self.attention_dropout, + scaling=self.scaling, + sliding_window=getattr(self.config, "sliding_window", None), + **kwargs, + ) + + attn_output = attn_output.reshape(*input_shape, -1).contiguous() + attn_output = self.o_proj(attn_output) + return attn_output, attn_weights + + +@use_kernel_forward_from_hub("RMSNorm") +class Phi3RMSNorm(nn.Module): + def __init__(self, hidden_size, eps: float = 1e-6) -> None: + """ + Phi3RMSNorm is equivalent to T5LayerNorm + """ + super().__init__() + self.weight = nn.Parameter(torch.ones(hidden_size)) + self.variance_epsilon = eps + + def forward(self, hidden_states: torch.Tensor) -> torch.Tensor: + input_dtype = hidden_states.dtype + hidden_states = hidden_states.to(torch.float32) + variance = hidden_states.pow(2).mean(-1, keepdim=True) + hidden_states = hidden_states * torch.rsqrt(variance + self.variance_epsilon) + return self.weight * hidden_states.to(input_dtype) + + def extra_repr(self): + return f"{tuple(self.weight.shape)}, eps={self.variance_epsilon}" + + +class Phi3DecoderLayer(GradientCheckpointingLayer): + def __init__(self, config: Phi3Config, layer_idx: int): + super().__init__() + self.hidden_size = config.hidden_size + self.self_attn = Phi3Attention(config=config, layer_idx=layer_idx) + self.mlp = Phi3MLP(config) + self.input_layernorm = Phi3RMSNorm(config.hidden_size, eps=config.rms_norm_eps) + self.post_attention_layernorm = Phi3RMSNorm(config.hidden_size, eps=config.rms_norm_eps) + self.config = config + self.resid_attn_dropout = nn.Dropout(config.resid_pdrop) + self.resid_mlp_dropout = nn.Dropout(config.resid_pdrop) + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.Tensor | None = None, + position_ids: torch.LongTensor | None = None, + past_key_values: Cache | None = None, + use_cache: bool | None = False, + cache_position: torch.LongTensor | None = None, + position_embeddings: tuple[torch.Tensor, torch.Tensor] | None = None, + **kwargs: Unpack[FlashAttentionKwargs], + ) -> tuple[torch.FloatTensor, tuple[torch.FloatTensor, torch.FloatTensor] | None]: + residual = hidden_states + hidden_states = self.input_layernorm(hidden_states) + + hidden_states, self_attn_weights = self.self_attn( + hidden_states=hidden_states, + attention_mask=attention_mask, + position_ids=position_ids, + past_key_values=past_key_values, + use_cache=use_cache, + cache_position=cache_position, + position_embeddings=position_embeddings, + **kwargs, + ) + hidden_states = residual + self.resid_attn_dropout(hidden_states) # main diff with Llama + + residual = hidden_states + hidden_states = self.post_attention_layernorm(hidden_states) + hidden_states = self.mlp(hidden_states) + hidden_states = residual + self.resid_mlp_dropout(hidden_states) # main diff with Llama + return hidden_states + + +@auto_docstring +class Phi3PreTrainedModel(PreTrainedModel): + config: Phi3Config + base_model_prefix = "model" + supports_gradient_checkpointing = True + _no_split_modules = ["Phi3DecoderLayer"] + _skip_keys_device_placement = ["past_key_values"] + _supports_flash_attn = True + _supports_sdpa = True + _supports_flex_attn = True + + _can_compile_fullgraph = True + _supports_attention_backend = True + _can_record_outputs = { + "hidden_states": Phi3DecoderLayer, + "attentions": Phi3Attention, + } + _version = "0.0.5" + + +@auto_docstring +class Phi3Model(Phi3PreTrainedModel): + def __init__(self, config: Phi3Config): + super().__init__(config) + self.padding_idx = config.pad_token_id + self.vocab_size = config.vocab_size + + self.embed_tokens = nn.Embedding(config.vocab_size, config.hidden_size, self.padding_idx) + self.layers = nn.ModuleList( + [Phi3DecoderLayer(config, layer_idx) for layer_idx in range(config.num_hidden_layers)] + ) + self.norm = Phi3RMSNorm(config.hidden_size, eps=config.rms_norm_eps) + self.rotary_emb = Phi3RotaryEmbedding(config=config) + self.gradient_checkpointing = False + + # Initialize weights and apply final processing + self.post_init() + + @merge_with_config_defaults + @capture_outputs + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.Tensor | None = None, + position_ids: torch.LongTensor | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.FloatTensor | None = None, + use_cache: bool | None = None, + cache_position: torch.LongTensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> BaseModelOutputWithPast: + if (input_ids is None) ^ (inputs_embeds is not None): + raise ValueError("You must specify exactly one of input_ids or inputs_embeds") + + if inputs_embeds is None: + inputs_embeds = self.embed_tokens(input_ids) + + if use_cache and past_key_values is None: + past_key_values = DynamicCache(config=self.config) + + if cache_position is None: + past_seen_tokens = past_key_values.get_seq_length() if past_key_values is not None else 0 + cache_position = torch.arange( + past_seen_tokens, past_seen_tokens + inputs_embeds.shape[1], device=inputs_embeds.device + ) + + if position_ids is None: + position_ids = cache_position.unsqueeze(0) + + mask_function = create_causal_mask if self.config.sliding_window is None else create_sliding_window_causal_mask + causal_mask = mask_function( + config=self.config, + inputs_embeds=inputs_embeds, + attention_mask=attention_mask, + cache_position=cache_position, + past_key_values=past_key_values, + position_ids=position_ids, + ) + + hidden_states = inputs_embeds + position_embeddings = self.rotary_emb(hidden_states, position_ids=position_ids) + + for decoder_layer in self.layers[: self.config.num_hidden_layers]: + hidden_states = decoder_layer( + hidden_states, + attention_mask=causal_mask, + position_ids=position_ids, + past_key_values=past_key_values, + use_cache=use_cache, + cache_position=cache_position, + position_embeddings=position_embeddings, + **kwargs, + ) + hidden_states = self.norm(hidden_states) + return BaseModelOutputWithPast( + last_hidden_state=hidden_states, + past_key_values=past_key_values if use_cache else None, + ) + + +@auto_docstring +class Phi3ForCausalLM(Phi3PreTrainedModel, GenerationMixin): + _tied_weights_keys = {"lm_head.weight": "model.embed_tokens.weight"} + _tp_plan = {"lm_head": "colwise_gather_output"} + _pp_plan = {"lm_head": (["hidden_states"], ["logits"])} + + def __init__(self, config): + super().__init__(config) + self.model = Phi3Model(config) + self.vocab_size = config.vocab_size + self.lm_head = nn.Linear(config.hidden_size, config.vocab_size, bias=False) + + # Initialize weights and apply final processing + self.post_init() + + @can_return_tuple + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.Tensor | None = None, + position_ids: torch.LongTensor | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.FloatTensor | None = None, + labels: torch.LongTensor | None = None, + use_cache: bool | None = None, + cache_position: torch.LongTensor | None = None, + logits_to_keep: int | torch.Tensor = 0, + **kwargs: Unpack[TransformersKwargs], + ) -> CausalLMOutputWithPast: + r""" + Example: + + ```python + >>> from transformers import AutoTokenizer, Phi3ForCausalLM + + >>> model = Phi3ForCausalLM.from_pretrained("meta-phi3/Phi3-2-7b-hf") + >>> tokenizer = AutoTokenizer.from_pretrained("meta-phi3/Phi3-2-7b-hf") + + >>> prompt = "Hey, are you conscious? Can you talk to me?" + >>> inputs = tokenizer(prompt, return_tensors="pt") + + >>> # Generate + >>> generate_ids = model.generate(inputs.input_ids, max_length=30) + >>> tokenizer.batch_decode(generate_ids, skip_special_tokens=True, clean_up_tokenization_spaces=False)[0] + "Hey, are you conscious? Can you talk to me?\nI'm not conscious, but I can talk to you." + ```""" + outputs: BaseModelOutputWithPast = self.model( + input_ids=input_ids, + attention_mask=attention_mask, + position_ids=position_ids, + past_key_values=past_key_values, + inputs_embeds=inputs_embeds, + use_cache=use_cache, + cache_position=cache_position, + **kwargs, + ) + + hidden_states = outputs.last_hidden_state + # Only compute necessary logits, and do not upcast them to float if we are not computing the loss + slice_indices = slice(-logits_to_keep, None) if isinstance(logits_to_keep, int) else logits_to_keep + logits = self.lm_head(hidden_states[:, slice_indices, :]) + + loss = None + if labels is not None: + loss = self.loss_function(logits=logits, labels=labels, vocab_size=self.config.vocab_size, **kwargs) + + return CausalLMOutputWithPast( + loss=loss, + logits=logits, + past_key_values=outputs.past_key_values, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + ) + + def prepare_inputs_for_generation( + self, + input_ids, + past_key_values=None, + attention_mask=None, + inputs_embeds=None, + cache_position=None, + position_ids=None, + use_cache=True, + logits_to_keep=None, + **kwargs, + ): + # Overwritten -- this model may need to switch between short and long rope, invalidating the cache in the + # process + + # When the first time input length reached long and short factor switching point, enforce re-compute cache + # It will cause downside of slower at this single token position, however, better than current failure. + if ( + past_key_values + and hasattr(self.config, "original_max_position_embeddings") + and input_ids.shape[1] >= self.config.original_max_position_embeddings + 1 + ): + past_length = cache_position[0] + if past_length <= self.config.original_max_position_embeddings: + past_key_values = None + + model_inputs = super().prepare_inputs_for_generation( + input_ids=input_ids, + past_key_values=past_key_values, + attention_mask=attention_mask, + inputs_embeds=inputs_embeds, + cache_position=cache_position, + position_ids=position_ids, + use_cache=use_cache, + logits_to_keep=logits_to_keep, + **kwargs, + ) + return model_inputs + + +class Phi3ForSequenceClassification(GenericForSequenceClassification, Phi3PreTrainedModel): + pass + + +class Phi3ForTokenClassification(GenericForTokenClassification, Phi3PreTrainedModel): + pass + + +__all__ = [ + "Phi3PreTrainedModel", + "Phi3Model", + "Phi3ForCausalLM", + "Phi3ForSequenceClassification", + "Phi3ForTokenClassification", +] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/phi3/modular_phi3.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/phi3/modular_phi3.py new file mode 100644 index 0000000000000000000000000000000000000000..7cb5c1730034767964514e3db691909d0b375101 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/phi3/modular_phi3.py @@ -0,0 +1,271 @@ +# Copyright 2024 Microsoft and the HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +"""PyTorch Phi-3 model.""" + +from collections.abc import Callable + +import torch +from torch import nn + +from ...activations import ACT2FN +from ...cache_utils import Cache +from ...generation import GenerationMixin +from ...modeling_flash_attention_utils import FlashAttentionKwargs +from ...modeling_utils import ALL_ATTENTION_FUNCTIONS +from ...processing_utils import Unpack +from ...utils import logging +from ..mistral.modeling_mistral import ( + MistralDecoderLayer, + MistralForCausalLM, + MistralForSequenceClassification, + MistralForTokenClassification, + MistralPreTrainedModel, + eager_attention_forward, + rotate_half, +) +from ..phi.modeling_phi import PhiRotaryEmbedding +from .configuration_phi3 import Phi3Config + + +logger = logging.get_logger(__name__) + +_CHECKPOINT_FOR_DOC = "microsoft/Phi-3-mini-4k-instruct" +_CONFIG_FOR_DOC = "Phi3Config" + + +class Phi3MLP(nn.Module): + def __init__(self, config): + super().__init__() + + self.config = config + self.gate_up_proj = nn.Linear(config.hidden_size, 2 * config.intermediate_size, bias=False) + self.down_proj = nn.Linear(config.intermediate_size, config.hidden_size, bias=False) + self.activation_fn = ACT2FN[config.hidden_act] + + def forward(self, hidden_states: torch.FloatTensor) -> torch.FloatTensor: + up_states = self.gate_up_proj(hidden_states) + + gate, up_states = up_states.chunk(2, dim=-1) + up_states = up_states * self.activation_fn(gate) + + return self.down_proj(up_states) + + +class Phi3RotaryEmbedding(PhiRotaryEmbedding): + pass + + +def apply_rotary_pos_emb(q, k, cos, sin, unsqueeze_dim=1): + """Applies Rotary Position Embedding to the query and key tensors. + + Args: + q (`torch.Tensor`): The query tensor. + k (`torch.Tensor`): The key tensor. + cos (`torch.Tensor`): The cosine part of the rotary embedding. + sin (`torch.Tensor`): The sine part of the rotary embedding. + unsqueeze_dim (`int`, *optional*, defaults to 1): + The 'unsqueeze_dim' argument specifies the dimension along which to unsqueeze cos[position_ids] and + sin[position_ids] so that they can be properly broadcasted to the dimensions of q and k. For example, note + that cos[position_ids] and sin[position_ids] have the shape [batch_size, seq_len, head_dim]. Then, if q and + k have the shape [batch_size, heads, seq_len, head_dim], then setting unsqueeze_dim=1 makes + cos[position_ids] and sin[position_ids] broadcastable to the shapes of q and k. Similarly, if q and k have + the shape [batch_size, seq_len, heads, head_dim], then set unsqueeze_dim=2. + Returns: + `tuple(torch.Tensor)` comprising of the query and key tensors rotated using the Rotary Position Embedding. + """ + cos = cos.unsqueeze(unsqueeze_dim) + sin = sin.unsqueeze(unsqueeze_dim) + + rotary_dim = cos.shape[-1] + q_rot, q_pass = q[..., :rotary_dim], q[..., rotary_dim:] + k_rot, k_pass = k[..., :rotary_dim], k[..., rotary_dim:] + + q_embed = torch.cat([(q_rot * cos) + (rotate_half(q_rot) * sin), q_pass], dim=-1) + k_embed = torch.cat([(k_rot * cos) + (rotate_half(k_rot) * sin), k_pass], dim=-1) + return q_embed, k_embed + + +class Phi3Attention(nn.Module): + """Multi-headed attention from 'Attention Is All You Need' paper""" + + def __init__(self, config: Phi3Config, layer_idx: int | None = None): + super().__init__() + self.config = config + self.layer_idx = layer_idx + self.head_dim = getattr(config, "head_dim", config.hidden_size // config.num_attention_heads) + self.num_key_value_groups = config.num_attention_heads // config.num_key_value_heads + self.num_key_value_heads = config.num_key_value_heads + self.scaling = self.head_dim**-0.5 + self.attention_dropout = config.attention_dropout + self.is_causal = True + + op_size = config.num_attention_heads * self.head_dim + 2 * (config.num_key_value_heads * self.head_dim) + self.o_proj = nn.Linear(config.num_attention_heads * self.head_dim, config.hidden_size, bias=False) + self.qkv_proj = nn.Linear(config.hidden_size, op_size, bias=False) + + def forward( + self, + hidden_states: torch.Tensor, + position_embeddings: tuple[torch.Tensor, torch.Tensor], + attention_mask: torch.Tensor | None, + past_key_values: Cache | None = None, + cache_position: torch.LongTensor | None = None, + **kwargs: Unpack[FlashAttentionKwargs], + ) -> tuple[torch.Tensor, torch.Tensor | None, tuple[torch.Tensor] | None]: + input_shape = hidden_states.shape[:-1] + hidden_shape = (*input_shape, -1, self.head_dim) + + qkv = self.qkv_proj(hidden_states) + query_pos = self.config.num_attention_heads * self.head_dim + query_states = qkv[..., :query_pos] + key_states = qkv[..., query_pos : query_pos + self.num_key_value_heads * self.head_dim] + value_states = qkv[..., query_pos + self.num_key_value_heads * self.head_dim :] + + query_states = query_states.view(hidden_shape).transpose(1, 2) + key_states = key_states.view(hidden_shape).transpose(1, 2) + value_states = value_states.view(hidden_shape).transpose(1, 2) + + cos, sin = position_embeddings + query_states, key_states = apply_rotary_pos_emb(query_states, key_states, cos, sin) + + if past_key_values is not None: + # sin and cos are specific to RoPE models; cache_position needed for the static cache + cache_kwargs = {"sin": sin, "cos": cos, "cache_position": cache_position} + key_states, value_states = past_key_values.update(key_states, value_states, self.layer_idx, cache_kwargs) + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, eager_attention_forward + ) + + attn_output, attn_weights = attention_interface( + self, + query_states, + key_states, + value_states, + attention_mask, + dropout=0.0 if not self.training else self.attention_dropout, + scaling=self.scaling, + sliding_window=getattr(self.config, "sliding_window", None), + **kwargs, + ) + + attn_output = attn_output.reshape(*input_shape, -1).contiguous() + attn_output = self.o_proj(attn_output) + return attn_output, attn_weights + + +class Phi3DecoderLayer(MistralDecoderLayer): + def __init__(self, config: Phi3Config, layer_idx: int): + super().__init__(config, layer_idx) + self.config = config + self.self_attn = Phi3Attention(config=config, layer_idx=layer_idx) + self.mlp = Phi3MLP(config) + self.resid_attn_dropout = nn.Dropout(config.resid_pdrop) + self.resid_mlp_dropout = nn.Dropout(config.resid_pdrop) + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.Tensor | None = None, + position_ids: torch.LongTensor | None = None, + past_key_values: Cache | None = None, + use_cache: bool | None = False, + cache_position: torch.LongTensor | None = None, + position_embeddings: tuple[torch.Tensor, torch.Tensor] | None = None, + **kwargs: Unpack[FlashAttentionKwargs], + ) -> tuple[torch.FloatTensor, tuple[torch.FloatTensor, torch.FloatTensor] | None]: + residual = hidden_states + hidden_states = self.input_layernorm(hidden_states) + + hidden_states, self_attn_weights = self.self_attn( + hidden_states=hidden_states, + attention_mask=attention_mask, + position_ids=position_ids, + past_key_values=past_key_values, + use_cache=use_cache, + cache_position=cache_position, + position_embeddings=position_embeddings, + **kwargs, + ) + hidden_states = residual + self.resid_attn_dropout(hidden_states) # main diff with Llama + + residual = hidden_states + hidden_states = self.post_attention_layernorm(hidden_states) + hidden_states = self.mlp(hidden_states) + hidden_states = residual + self.resid_mlp_dropout(hidden_states) # main diff with Llama + return hidden_states + + +class Phi3PreTrainedModel(MistralPreTrainedModel): + _version = "0.0.5" + + +class Phi3ForCausalLM(MistralForCausalLM): + def prepare_inputs_for_generation( + self, + input_ids, + past_key_values=None, + attention_mask=None, + inputs_embeds=None, + cache_position=None, + position_ids=None, + use_cache=True, + logits_to_keep=None, + **kwargs, + ): + # Overwritten -- this model may need to switch between short and long rope, invalidating the cache in the + # process + + # When the first time input length reached long and short factor switching point, enforce re-compute cache + # It will cause downside of slower at this single token position, however, better than current failure. + if ( + past_key_values + and hasattr(self.config, "original_max_position_embeddings") + and input_ids.shape[1] >= self.config.original_max_position_embeddings + 1 + ): + past_length = cache_position[0] + if past_length <= self.config.original_max_position_embeddings: + past_key_values = None + + model_inputs = GenerationMixin.prepare_inputs_for_generation( + self, + input_ids=input_ids, + past_key_values=past_key_values, + attention_mask=attention_mask, + inputs_embeds=inputs_embeds, + cache_position=cache_position, + position_ids=position_ids, + use_cache=use_cache, + logits_to_keep=logits_to_keep, + **kwargs, + ) + return model_inputs + + +class Phi3ForSequenceClassification(MistralForSequenceClassification): + pass + + +class Phi3ForTokenClassification(MistralForTokenClassification): + pass + + +__all__ = [ + "Phi3PreTrainedModel", + "Phi3Model", # noqa: F822 + "Phi3ForCausalLM", + "Phi3ForSequenceClassification", + "Phi3ForTokenClassification", +] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/phi4_multimodal/__init__.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/phi4_multimodal/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..c4e2e599f57a8f9fe23254a46ff6fda67e82f13b --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/phi4_multimodal/__init__.py @@ -0,0 +1,32 @@ +# Copyright 2025 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + + +from typing import TYPE_CHECKING + +from ...utils import _LazyModule +from ...utils.import_utils import define_import_structure + + +if TYPE_CHECKING: + from .configuration_phi4_multimodal import * + from .feature_extraction_phi4_multimodal import * + from .image_processing_phi4_multimodal_fast import * + from .modeling_phi4_multimodal import * + from .processing_phi4_multimodal import * +else: + import sys + + _file = globals()["__file__"] + sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__) diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/phi4_multimodal/configuration_phi4_multimodal.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/phi4_multimodal/configuration_phi4_multimodal.py new file mode 100644 index 0000000000000000000000000000000000000000..1a46d63aaba06f0bad2ce7712849841f1aaa9c6c --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/phi4_multimodal/configuration_phi4_multimodal.py @@ -0,0 +1,480 @@ +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# This file was automatically generated from src/transformers/models/phi4_multimodal/modular_phi4_multimodal.py. +# Do NOT edit this file manually as any edits will be overwritten by the generation of +# the file from the modular. If any change should be done, please apply the change to the +# modular_phi4_multimodal.py file directly. One of our CI enforces this. +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# Copyright 2025 Microsoft and the HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import math + +from ...configuration_utils import PreTrainedConfig +from ...modeling_rope_utils import RopeParameters + + +class Phi4MultimodalVisionConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`Phi4MultimodalVisionModel`]. It is used to instantiate a + Phi4Multimodal vision encoder according to the specified arguments, defining the model architecture. Instantiating a + configuration with the defaults will yield a similar configuration to that of the vision encoder of + [microsoft/Phi-4-multimodal-instruct](https://huggingface.co/microsoft/Phi-4-multimodal-instruct) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + hidden_size (`int`, *optional*, defaults to 1152): + Dimensionality of the encoder layers and the pooler layer. + intermediate_size (`int`, *optional*, defaults to 4304): + Dimensionality of the "intermediate" (i.e., feed-forward) layer in the Transformer encoder. + num_hidden_layers (`int`, *optional*, defaults to 27): + Number of hidden layers in the Transformer encoder. + num_attention_heads (`int`, *optional*, defaults to 16): + Number of attention heads for each attention layer in the Transformer encoder. + num_channels (`int`, *optional*, defaults to 3): + Number of channels in the input images. + image_size (`int`, *optional*, defaults to 448): + The size (resolution) of each image. + patch_size (`int`, *optional*, defaults to 14): + The size (resolution) of each patch. + hidden_act (`str` or `function`, *optional*, defaults to `"gelu_pytorch_tanh"`): + The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`, + `"relu"`, `"selu"` and `"gelu_new"` `"quick_gelu"` are supported. + layer_norm_eps (`float`, *optional*, defaults to 1e-06): + The epsilon used by the layer normalization layers. + attention_dropout (`float`, *optional*, defaults to 0.0): + The dropout ratio for the attention probabilities. + crop_size (`int`, *optional*, defaults to 448): + Crop size for the input images. + image_token_id (`int`, *optional*, defaults to 200010): + The image token id. + feature_layer (`int`, *optional*, defaults to -2): + The index of the layer of the encoder from which to extract image features. + + Example: + + ```python + >>> from transformers import Phi4MultimodalVisionConfig + + >>> # Initializing a Phi4MultimodalVisionConfig with microsoft/Phi-4-multimodal-instruct style configuration + >>> configuration = Phi4MultimodalVisionConfig() + ```""" + + model_type = "phi4_multimodal_vision" + base_config_key = "vision_config" + + def __init__( + self, + hidden_size=1152, + intermediate_size=4304, + num_hidden_layers=27, + num_attention_heads=16, + num_channels=3, + image_size=448, + patch_size=14, + hidden_act="gelu_pytorch_tanh", + layer_norm_eps=1e-6, + attention_dropout=0.0, + crop_size: int = 448, + image_token_id: int = 200010, + feature_layer: int = -2, + **kwargs, + ): + super().__init__(**kwargs) + + self.hidden_size = hidden_size + self.intermediate_size = intermediate_size + self.num_hidden_layers = num_hidden_layers + self.num_attention_heads = num_attention_heads + self.num_channels = num_channels + self.patch_size = patch_size + self.image_size = image_size + self.attention_dropout = attention_dropout + self.layer_norm_eps = layer_norm_eps + self.hidden_act = hidden_act + self.crop_size = crop_size + self.image_token_id = image_token_id + self.feature_layer = feature_layer + + +class Phi4MultimodalAudioConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`Phi4MultimodalAudioModel`]. It is used to instantiate a + Phi4Multimodal audio encoder according to the specified arguments, defining the model architecture. Instantiating a + configuration with the defaults will yield a similar configuration to that of the audio encoder of + [microsoft/Phi-4-multimodal-instruct](https://huggingface.co/microsoft/Phi-4-multimodal-instruct) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + hidden_size (`int`, *optional*, defaults to 1024): + Dimensionality of the encoder layers. + intermediate_size (`int`, *optional*, defaults to 1536): + Dimensionality of the "intermediate" (i.e., feed-forward) layer in the Transformer encoder. + num_blocks (`int`, *optional*, defaults to 24): + Number of hidden layers in the Transformer encoder. + num_attention_heads (`int`, *optional*, defaults to 16): + Number of attention heads for each attention layer in the Transformer encoder. + activation (`str`, *optional*, defaults to `"swish"`): + The non-linear activation function in the MLPs. + chunk_size (`int`, *optional*, defaults to -1): + The chunk size to create the masks. + left_chunk (`int`, *optional*, defaults to 18): + The left chunk to create the masks. + dropout_rate (`float`, *optional*, defaults to 0.0): + The dropout ratio. + ext_pw_out_channel (`int`, *optional*, defaults to 1024): + Number of out channels in the point-wise conv modules. + depthwise_separable_out_channel (`int`, *optional*, defaults to 1024): + Number of out channels in the depth-wise separable conv modules. + depthwise_multiplier (`int`, *optional*, defaults to 1): + Input size multiplier for the depth-wise separable conv modules. + kernel_size (`int`, *optional*, defaults to 3): + Kernel size for the depth-wise separable conv modules. + conv_activation (`str`, *optional*, defaults to `"swish"`): + The non-linear activation function in the conv modules. + input_size (`int`, *optional*, defaults to 80): + Input size for the audio model. + conv_glu_type (`str`, *optional*, defaults to `"swish"`): + The non-linear activation function in the point-wise conv modules. + time_reduction (`int`, *optional*, defaults to 8): + Time reduction (subsampling factor). + bias_max_distance (`int`, *optional*, defaults to 1000): + Max distance for the relative attention bias module. + bias_symmetric (`bool`, *optional*, defaults to `False`): + Whether the relative attention bias should be symmetric or not. + nemo_activation (`str`, *optional*, defaults to `"relu"`): + The non-linear activation function in the nemo conv modules. + nemo_conv_channels (`int`, *optional*, defaults to 1024): + Number of channels in the nemo conv modules. + downsample_rate (`int`, *optional*, defaults to 1): + Downsample rate for the audio feature extractor. + initializer_range (`float`, *optional*, defaults to 0.02): + The standard deviation of the truncated_normal_initializer for initializing all weight matrices. + audio_token_id (`int`, *optional*, defaults to 200011): + The audio token id. + feature_layer (`int`, *optional*, defaults to -2): + The index of the layer of the encoder from which to extract audio features. + + Example: + + ```python + >>> from transformers import Phi4MultimodalAudioConfig + + >>> # Initializing a Phi4MultimodalAudioConfig with microsoft/Phi-4-multimodal-instruct style configuration + >>> configuration = Phi4MultimodalAudioConfig() + ```""" + + model_type = "phi4_multimodal_audio" + + def __init__( + self, + hidden_size: int = 1024, + intermediate_size: int = 1536, + num_blocks: int = 24, + num_attention_heads: int = 16, + activation: str = "swish", + chunk_size: int = -1, + left_chunk: int = 18, + dropout_rate: float = 0.0, + ext_pw_out_channel: int = 1024, + depthwise_separable_out_channel: int = 1024, + depthwise_multiplier: int = 1, + kernel_size: int = 3, + conv_activation: str = "swish", + input_size: int = 80, + conv_glu_type: str = "swish", + time_reduction: int = 8, + bias_max_distance: int = 1000, + bias_symmetric: bool = False, + nemo_activation: str = "relu", + nemo_conv_channels: int = 1024, + downsample_rate: int = 1, + initializer_range: float = 0.02, + audio_token_id: int = 200011, + feature_layer: int = -2, + **kwargs, + ): + super().__init__(**kwargs) + self.hidden_size = hidden_size + self.num_attention_heads = num_attention_heads + self.intermediate_size = intermediate_size + self.activation = activation + self.chunk_size = chunk_size + self.left_chunk = left_chunk + self.num_blocks = num_blocks + self.dropout_rate = dropout_rate + self.ext_pw_out_channel = ext_pw_out_channel + self.depthwise_separable_out_channel = depthwise_separable_out_channel + self.depthwise_multiplier = depthwise_multiplier + self.kernel_size = kernel_size + self.conv_activation = conv_activation + self.input_size = input_size + self.conv_glu_type = conv_glu_type + self.time_reduction = time_reduction + self.bias_max_distance = bias_max_distance + self.bias_symmetric = bias_symmetric + self.nemo_activation = nemo_activation + self.nemo_conv_channels = nemo_conv_channels + self.downsample_rate = downsample_rate + self.audio_token_id = audio_token_id + self.initializer_range = initializer_range + self.feature_layer = feature_layer + + if time_reduction % 2 != 0: + raise ValueError("`time_reduction` should be a multiple of 2!") + length = input_size + for _ in range(int(math.log2(time_reduction))): + length = math.floor((length - 1) / 2 + 1) + self.nemo_final_size = length + + +class Phi4MultimodalConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`Phi4MultimodalModel`]. It is used to instantiate a + Phi4Multimodal model according to the specified arguments, defining the model architecture. Instantiating a configuration + with the defaults will yield a similar configuration to that of the + [microsoft/Phi-4-multimodal-instruct](https://huggingface.co/microsoft/Phi-4-multimodal-instruct) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + vocab_size (`int`, *optional*, defaults to 200064): + Vocabulary size of the Phi-3 model. Defines the number of different tokens that can be represented by the + `inputs_ids` passed when calling [`Phi3Model`]. + hidden_size (`int`, *optional*, defaults to 3072): + Dimension of the hidden representations. + intermediate_size (`int`, *optional*, defaults to 8192): + Dimension of the MLP representations. + num_hidden_layers (`int`, *optional*, defaults to 32): + Number of hidden layers in the Transformer decoder. + num_attention_heads (`int`, *optional*, defaults to 32): + Number of attention heads for each attention layer in the Transformer decoder. + num_key_value_heads (`int`, *optional*, defaults to 8): + This is the number of key_value heads that should be used to implement Grouped Query Attention. If + `num_key_value_heads=num_attention_heads`, the model will use Multi Head Attention (MHA), if + `num_key_value_heads=1` the model will use Multi Query Attention (MQA) otherwise GQA is used. When + converting a multi-head checkpoint to a GQA checkpoint, each group key and value head should be constructed + by meanpooling all the original heads within that group. For more details, check out [this + paper](https://huggingface.co/papers/2305.13245). If it is not specified, will default to + `num_attention_heads`. + resid_pdrop (`float`, *optional*, defaults to 0.0): + Dropout probability for mlp outputs. + embd_pdrop (`int`, *optional*, defaults to 0.0): + The dropout ratio for the embeddings. + attention_dropout (`float`, *optional*, defaults to 0.0): + The dropout ratio after computing the attention scores. + hidden_act (`str` or `function`, *optional*, defaults to `"silu"`): + The non-linear activation function (function or string) in the decoder. + max_position_embeddings (`int`, *optional*, defaults to 131072): + The maximum sequence length that this model might ever be used with. + initializer_range (`float`, *optional*, defaults to 0.02): + The standard deviation of the truncated_normal_initializer for initializing all weight matrices. + rms_norm_eps (`float`, *optional*, defaults to 1e-05): + The epsilon value used for the RMSNorm. + use_cache (`bool`, *optional*, defaults to `True`): + Whether or not the model should return the last key/values attentions (not used by all models). Only + relevant if `config.is_decoder=True`. Whether to tie weight embeddings or not. + tie_word_embeddings (`bool`, *optional*, defaults to `False`): + Whether to tie weight embeddings + rope_parameters (`RopeParameters`, *optional*): + Dictionary containing the configuration parameters for the RoPE embeddings. The dictionary should contain + a value for `rope_theta` and optionally parameters used for scaling in case you want to use RoPE + with longer `max_position_embeddings`. + bos_token_id (`int`, *optional*, defaults to 199999): + The id of the "beginning-of-sequence" token. + eos_token_id (`int` or `list[int]`, *optional*, defaults to `[199999, 200020]`): + The id of the "end-of-sequence" token. + pad_token_id (`int`, *optional*, defaults to 199999): + The id of the padding token. + original_max_position_embeddings (`int`, *optional*, defaults to 4096): + The maximum sequence length that this model was trained with. This is used to determine the size of the + original RoPE embeddings when using long scaling. + sliding_window (`int`, *optional*): + Sliding window attention window size. If `None`, no sliding window is applied. + vision_config (`Phi4MultimodalVisionConfig` or `dict`, *optional*): + The vision config for the underlying image embedding model. If not provided, will default to the configuration + used to instantiate a model similar in architecture as + [microsoft/Phi-4-multimodal-instruct](https://huggingface.co/microsoft/Phi-4-multimodal-instruct). + audio_config (`Phi4MultimodalAudioConfig` or `dict`, *optional*): + The audio config for the underlying audio embedding model. If not provided, will default to the configuration + used to instantiate a model similar in architecture as + [microsoft/Phi-4-multimodal-instruct](https://huggingface.co/microsoft/Phi-4-multimodal-instruct). + + Example: + + ```python + >>> from transformers import Phi4MultimodalModel, Phi4MultimodalConfig + + >>> # Initializing a Phi4Multimodal style configuration + >>> configuration = Phi4MultimodalConfig.from_pretrained("microsoft/Phi-4-multimodal-instruct") + + >>> # Initializing a model from the configuration + >>> model = Phi4MultimodalModel(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "phi4_multimodal" + keys_to_ignore_at_inference = ["past_key_values"] + base_model_tp_plan = { + "layers.*.self_attn.qkv_proj": "colwise_gather_output", # we need to replicate here due to the slicing of qkv + "layers.*.self_attn.o_proj": "rowwise_split_input", # input is replicated due to the slicing of qkv + "layers.*.mlp.gate_up_proj": "colwise_gather_output", # we need to replicate here due to the `chunk` operation + "layers.*.mlp.down_proj": "rowwise_split_input", # input is replicated due to the `chunk` operation + } + base_model_pp_plan = { + "embed_tokens": (["input_ids"], ["inputs_embeds"]), + "layers": (["hidden_states", "attention_mask"], ["hidden_states"]), + "norm": (["hidden_states"], ["hidden_states"]), + } + + sub_configs = {"audio_config": Phi4MultimodalAudioConfig, "vision_config": Phi4MultimodalVisionConfig} + + def __init__( + self, + vocab_size: int | None = 200064, + hidden_size: int | None = 3072, + intermediate_size: int | None = 8192, + num_hidden_layers: int | None = 32, + num_attention_heads: int | None = 32, + num_key_value_heads: int | None = 8, + resid_pdrop: float | None = 0.0, + embd_pdrop: float | None = 0.0, + attention_dropout: float | None = 0.0, + hidden_act: str | None = "silu", + max_position_embeddings: int | None = 131072, + initializer_range: float | None = 0.02, + rms_norm_eps: int | None = 1e-5, + use_cache: bool | None = True, + tie_word_embeddings: bool | None = False, + rope_parameters: RopeParameters | dict[str, RopeParameters] | None = None, + bos_token_id: int | None = 199999, + eos_token_id: list[int] | None = [199999, 200020], + pad_token_id: int | None = 199999, + original_max_position_embeddings: int | None = 4096, + sliding_window: int | None = None, + vision_config: dict | None = None, + audio_config: dict | None = None, + **kwargs, + ): + if isinstance(vision_config, dict): + vision_config = Phi4MultimodalVisionConfig(**vision_config) + elif vision_config is None: + vision_config = Phi4MultimodalVisionConfig() + self.vision_config = vision_config + + if isinstance(audio_config, dict): + audio_config = Phi4MultimodalAudioConfig(**audio_config) + elif audio_config is None: + audio_config = Phi4MultimodalAudioConfig() + self.audio_config = audio_config + self.vocab_size = vocab_size + self.hidden_size = hidden_size + self.intermediate_size = intermediate_size + self.num_hidden_layers = num_hidden_layers + self.num_attention_heads = num_attention_heads + + if num_key_value_heads is None: + num_key_value_heads = num_attention_heads + + self.num_key_value_heads = num_key_value_heads + self.resid_pdrop = resid_pdrop + self.embd_pdrop = embd_pdrop + self.attention_dropout = attention_dropout + self.hidden_act = hidden_act + self.max_position_embeddings = max_position_embeddings + self.original_max_position_embeddings = original_max_position_embeddings + self.initializer_range = initializer_range + self.rms_norm_eps = rms_norm_eps + self.use_cache = use_cache + self.rope_parameters = rope_parameters + kwargs.setdefault("partial_rotary_factor", 1.0) # assign default for BC + self.sliding_window = sliding_window + + self.bos_token_id = bos_token_id + self.eos_token_id = eos_token_id + self.pad_token_id = pad_token_id + self.tie_word_embeddings = tie_word_embeddings + super().__init__(**kwargs) + + def convert_rope_params_to_dict( + self, default_theta: int | float = 10_000.0, ignore_keys: set | None = None, **kwargs + ): + rope_scaling = kwargs.pop("rope_scaling", None) + self.rope_parameters = rope_scaling or self.rope_parameters + self.rope_parameters = self.rope_parameters if self.rope_parameters is not None else {} + + # Standardize and validate the correctness of rotary position embeddings parameters + self.rope_parameters.setdefault("rope_theta", kwargs.pop("rope_theta", default_theta)) + self.rope_parameters.setdefault("partial_rotary_factor", kwargs["partial_rotary_factor"]) + self.standardize_rope_params() + + # For backward compatibility if previous version used "su" or "yarn" + rope_parameters_type = self.rope_parameters.get("rope_type", None) + if rope_parameters_type is not None and rope_parameters_type in ["su", "yarn"]: + self.rope_parameters["rope_type"] = "longrope" + self.validate_rope(ignore_keys=ignore_keys) + return kwargs + + def validate_rope(self, ignore_keys: set | None = None): + """ + Validate the `rope_parameters` configuration. + """ + super().validate_rope(ignore_keys=ignore_keys) + + # Run Phi4Multimodal specific validation + if not isinstance(self.rope_parameters, dict): + raise ValueError(f"`rope_parameters` must be a dictionary but got {self.rope_parameters}") + rope_parameters_type = self.rope_parameters.get("rope_type", None) + rope_parameters_short_factor = self.rope_parameters.get("short_factor", None) + rope_parameters_long_factor = self.rope_parameters.get("long_factor", None) + rotary_ndims = int( + self.hidden_size // self.num_attention_heads * self.rope_parameters["partial_rotary_factor"] + ) + if rope_parameters_type not in ["default", "longrope"]: + raise ValueError(f"`rope_parameters`'s type field must be one of ['longrope'], got {rope_parameters_type}") + + if rope_parameters_short_factor is not None: + if not ( + isinstance(rope_parameters_short_factor, list) + and all(isinstance(x, (int, float)) for x in rope_parameters_short_factor) + ): + raise ValueError( + f"`rope_parameters`'s short_factor field must be a list of numbers, got {rope_parameters_short_factor}" + ) + if not len(rope_parameters_short_factor) == rotary_ndims // 2: + raise ValueError( + f"`rope_parameters`'s short_factor field must have length {rotary_ndims // 2}, got {len(rope_parameters_short_factor)}" + ) + + if rope_parameters_long_factor is not None: + if not ( + isinstance(rope_parameters_long_factor, list) + and all(isinstance(x, (int, float)) for x in rope_parameters_long_factor) + ): + raise ValueError( + f"`rope_parameters`'s long_factor field must be a list of numbers, got {rope_parameters_long_factor}" + ) + if not len(rope_parameters_long_factor) == rotary_ndims // 2: + raise ValueError( + f"`rope_parameters`'s long_factor field must have length {rotary_ndims // 2}, got {len(rope_parameters_long_factor)}" + ) + + +__all__ = ["Phi4MultimodalVisionConfig", "Phi4MultimodalAudioConfig", "Phi4MultimodalConfig"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/phi4_multimodal/feature_extraction_phi4_multimodal.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/phi4_multimodal/feature_extraction_phi4_multimodal.py new file mode 100644 index 0000000000000000000000000000000000000000..9ce98251e50e028d48a3e8fc21929ae9ac3d32d2 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/phi4_multimodal/feature_extraction_phi4_multimodal.py @@ -0,0 +1,281 @@ +# Copyright 2024 Microsoft and the HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +""" +Processor class for Phi4Multimodal +""" + +import numpy as np + +from ...audio_utils import AudioInput, mel_filter_bank +from ...feature_extraction_sequence_utils import SequenceFeatureExtractor +from ...image_processing_utils import BatchFeature +from ...utils import TensorType, is_torch_available, logging + + +if is_torch_available(): + import torch + + +logger = logging.get_logger(__name__) + + +class Phi4MultimodalFeatureExtractor(SequenceFeatureExtractor): + model_input_names = ["audio_input_features", "audio_embed_sizes", "audio_attention_mask"] + + def __init__( + self, + feature_size: int = 80, + sampling_rate: int = 16000, + hop_length: int = 160, + n_fft: int = 512, + win_length: int = 400, + preemphasis: float = 0.97, + padding_value: float = 0.0, + audio_compression_rate: int = 8, + audio_downsample_rate: int = 1, + audio_feat_stride: int = 1, + mel_min_frequency: float = 0, + mel_max_frequency: float = 7690, + **kwargs, + ): + super().__init__(feature_size=feature_size, sampling_rate=sampling_rate, padding_value=padding_value, **kwargs) + + self.hop_length = hop_length + self.n_fft = n_fft + self.win_length = win_length + self.preemphasis = preemphasis + self.padding_value = padding_value + self.audio_compression_rate = audio_compression_rate + self.audio_downsample_rate = audio_downsample_rate + self.audio_feat_stride = audio_feat_stride + + self.mel_filters = mel_filter_bank( + num_frequency_bins=self.n_fft // 2 + 1, + num_mel_filters=self.feature_size, + min_frequency=mel_min_frequency, + max_frequency=mel_max_frequency, + sampling_rate=self.sampling_rate, + triangularize_in_mel_space=True, + mel_scale="kaldi", + ) + + def __call__( + self, + raw_speech: AudioInput, + sampling_rate: int | None = None, + pad_to_multiple_of: int | None = None, + padding: str | None = "longest", + max_length: int | None = None, + truncation: bool = False, + return_tensors: str | TensorType | None = None, + return_attention_mask: bool | None = True, + device: str | None = "cpu", + **kwargs, + ) -> BatchFeature: + """ + Main method to featurize and prepare for the model one or several audio sequence(s). Implementation uses PyTorch for + the STFT computation if available, otherwise a slower NumPy based one. + + Args: + raw_speech (`np.ndarray`, `torch.Tensor`, `list[np.ndarray]`, `list[torch.Tensor]`): + The sequence or batch of sequences to be processed. Each sequence can be a numpy array or PyTorch tensor. + For batched inputs, sequences can be a list of numpy arrays or PyTorch tensors, or a single numpy array or + PyTorch tensor with first dimension being the batch size. + sampling_rate (`int`, *optional*): + The sampling rate at which the `raw_speech` input was sampled. It is strongly recommended to pass + `sampling_rate` at the forward call to prevent silent errors. + pad_to_multiple_of (`int`, *optional*, defaults to None): + If set will pad the sequence to a multiple of the provided value. + padding (`str`, *optional*, defaults to "longest"): + Padding strategy. Can be "longest" to pad to the longest sequence in the batch, or a specific length. + max_length (`int`, *optional*): + Maximum length of the returned list and optionally padding length. + truncation (`bool`, *optional*, defaults to False): + Activates truncation to cut input sequences longer than *max_length* to *max_length*. + return_tensors (`str` or [`~utils.TensorType`], *optional*): + If set, will return tensors instead of numpy arrays. Acceptable values are: + - `'pt'`: Return PyTorch `torch.Tensor` objects. + - `'np'`: Return Numpy `np.ndarray` objects. + return_attention_mask (`bool`, *optional*, defaults to `True`): + Whether to return the extracted audio input features' attention mask. + device (`str`, *optional*, defaults to "cpu"): + Specifies the device for computation of the audio features. (e.g., "cpu", "cuda") + + Returns: + [`BatchFeature`]: A [`BatchFeature`] with the following fields: + - **audio_input_features** -- Audio features extracted from the raw audio input, shape (batch_size, max_feature_length, feature_size). + - **audio_lengths** -- Length of each audio sample in the batch, shape (batch_size,). + - **audio_attention_mask** -- Attention mask for the audio input, shape (batch_size, max_feature_length). + If `return_tensors` is not specified, the fields will be PyTorch tensors if PyTorch is available, otherwise NumPy arrays. + """ + if sampling_rate is not None: + if sampling_rate != self.sampling_rate: + raise ValueError( + f"The model corresponding to this feature extractor: {self.__class__.__name__} was trained using a" + f" sampling rate of {self.sampling_rate}. Please make sure that the provided `raw_speech` input" + f" was sampled with {self.sampling_rate} and not {sampling_rate}." + ) + else: + logger.warning( + f"It is strongly recommended to pass the `sampling_rate` argument to `{self.__class__.__name__}()`. " + "Failing to do so can result in silent errors that might be hard to debug." + ) + + # Convert to torch tensor + if isinstance(raw_speech, np.ndarray): + raw_speech = torch.tensor(raw_speech) + elif isinstance(raw_speech, (list, tuple)) and isinstance(raw_speech[0], np.ndarray): + raw_speech = [torch.tensor(speech) for speech in raw_speech] + + is_batched_torch = isinstance(raw_speech, torch.Tensor) and len(raw_speech.shape) > 1 + if is_batched_torch and len(raw_speech.shape) > 2: + logger.warning( + f"Only mono-channel audio is supported for input to {self.__class__.__name__}. " + "We will take the mean of the channels to convert to mono." + ) + raw_speech = raw_speech.mean(-1) + + is_batched_sequence = isinstance(raw_speech, (list, tuple)) + if is_batched_sequence: + for speech in raw_speech: + if len(speech.shape) > 1: + logger.warning( + f"Only mono-channel audio is supported for input to {self.__class__.__name__}. " + "We will take the mean of the channels to convert to mono." + ) + speech = speech.mean(-1) + + if is_batched_torch or is_batched_sequence: + raw_speech = [speech[:, None].to(torch.float32) for speech in raw_speech] + else: + raw_speech = [raw_speech[:, None].to(torch.float32)] + + audio_lengths = [len(speech) for speech in raw_speech] + + # convert into correct format for padding + batched_speech = BatchFeature(data={"audio_input_features": raw_speech, "audio_lengths": audio_lengths}) + padded_inputs = self.pad( + batched_speech, + padding=padding, + max_length=max_length, + truncation=truncation, + pad_to_multiple_of=pad_to_multiple_of, + return_tensors="pt", + ) + input_features = padded_inputs.audio_input_features.squeeze(-1) + audio_lengths = padded_inputs.audio_lengths + + input_features = self._torch_extract_fbank_features(input_features, audio_lengths, device) + + feature_lengths = (audio_lengths - self.win_length) // self.hop_length + 1 + feature_lengths = feature_lengths * self.audio_feat_stride + audio_embed_sizes = self._compute_audio_embed_size(feature_lengths) + + feature_attention_mask = ( + torch.arange(0, feature_lengths.max()) if is_torch_available() else np.arange(0, feature_lengths.max()) + ) + feature_attention_mask = ( + feature_attention_mask[None, :] < feature_lengths[:, None] if len(feature_lengths) > 1 else None + ) + + data = { + "audio_input_features": input_features, + "audio_embed_sizes": audio_embed_sizes, + } + if feature_attention_mask is not None and return_attention_mask: + data["audio_attention_mask"] = feature_attention_mask + + return BatchFeature(data=data, tensor_type=return_tensors) + + # TODO; @eustlb, move this to audio_utils in a general spectogram_batch function that handles torch and numpy + def _torch_extract_fbank_features( + self, waveform: "torch.FloatTensor", audio_lengths: "torch.Tensor", device: str = "cpu" + ) -> "torch.FloatTensor": + """ + Compute the log mel-scaled spectrogram of batched waveforms using PyTorch's FFT implementation. + + Args: + waveform (torch.FloatTensor` of shape `(batch_size, max_audio_length)`): + The batched waveforms. + audio_lengths (`torch.Tensor` of shape `(batch_size,)`): + The lengths of the waveforms along the max_audio_length dimension. + device (`str`, *optional*, defaults to "cpu"): + The device to run the computation on. (e.g., "cpu", "cuda") + + Returns: + `torch.FloatTensor` of shape `(batch_size, max_feature_length, feature_size)`: + The log mel-scaled spectrogram of the batched waveforms. + """ + fft_window = torch.hamming_window(self.win_length, periodic=False, device=device, dtype=torch.float64) + + # batched implementation + batch_size = waveform.shape[0] + frames = waveform.unfold(-1, self.win_length, self.hop_length) + + # --- + # the unbatched (and unpaded) original implementation skips last few audio values that can't be included in a frame + # we need to ensure that the corresponding frames for the padded input also mask these values + if batch_size > 1: + frames = frames.clone() + # concerned batch indices + to_mask_batch_idxs = torch.arange(batch_size)[audio_lengths != audio_lengths.max()] + if to_mask_batch_idxs.numel() > 0: + batch_idxs_down = (audio_lengths[to_mask_batch_idxs] - self.win_length) // self.hop_length + 1 + batch_idxs_up = (audio_lengths[to_mask_batch_idxs] // self.hop_length) - 1 + offset_idx = batch_idxs_down.min() + max_idx = batch_idxs_up.max() + + mask = torch.arange(max_idx - offset_idx, device=device).expand(to_mask_batch_idxs.shape[0], -1) + mask = ((batch_idxs_down - offset_idx).unsqueeze(1) <= mask) & ( + mask < (batch_idxs_up - offset_idx).unsqueeze(1) + ) + mask = mask.unsqueeze(-1).expand(-1, -1, self.win_length) + masked_frames = frames[to_mask_batch_idxs, offset_idx:max_idx].masked_fill_(mask, 0) + frames[to_mask_batch_idxs, offset_idx:max_idx] = masked_frames + # --- + + # apply pre-emphasis first order filter on fft windows + frames_prev = torch.roll(frames, 1, dims=-1) + frames_prev[:, :, 0] = frames_prev[:, :, 1] + frames = (frames - self.preemphasis * frames_prev) * 32768 + + # apply fft + S = torch.fft.rfft(fft_window * frames.view(-1, self.win_length), n=self.n_fft, dim=1) + S = S.view(frames.shape[0], -1, S.shape[-1]) + S = S.to(torch.complex64) + + spec = torch.abs(S) + spec_power = spec**2 + + # apply triangular mel filter bank + mel_filters = torch.from_numpy(self.mel_filters).to(device, torch.float32) + log_spec = torch.clamp(spec_power @ mel_filters, min=1.0) + log_spec = torch.log(log_spec) + + return log_spec + + def _compute_audio_embed_size(self, audio_frames): + integer = audio_frames // self.audio_compression_rate + remainder = audio_frames % self.audio_compression_rate + result = integer + (remainder > 0).to(integer.dtype) + + integer = result // self.audio_downsample_rate + remainder = result % self.audio_downsample_rate + result = integer + (remainder > 0).to(integer.dtype) # qformer compression + + return result + + +__all__ = ["Phi4MultimodalFeatureExtractor"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/phi4_multimodal/image_processing_phi4_multimodal_fast.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/phi4_multimodal/image_processing_phi4_multimodal_fast.py new file mode 100644 index 0000000000000000000000000000000000000000..8b68c131135b23c430d425048dea7ca82869abfc --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/phi4_multimodal/image_processing_phi4_multimodal_fast.py @@ -0,0 +1,257 @@ +# Copyright 2025 Microsoft and the HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import math +from typing import Optional + +import torch +import torchvision.transforms.v2.functional as tvF + +from ...image_processing_utils_fast import ( + BaseImageProcessorFast, + BatchFeature, + Unpack, +) +from ...image_utils import ImageInput, PILImageResampling, SizeDict +from ...processing_utils import ImagesKwargs +from ...utils import ( + TensorType, + auto_docstring, + logging, +) + + +logger = logging.get_logger(__name__) + + +class Phi4MultimodalImageProcessorKwargs(ImagesKwargs, total=False): + r""" + patch_size (`int`, *optional*): + The size of the patch. + dynamic_hd (`int`, *optional*): + The maximum number of crops per image. + """ + + patch_size: int + dynamic_hd: int + + +@auto_docstring +class Phi4MultimodalImageProcessorFast(BaseImageProcessorFast): + resample = PILImageResampling.BICUBIC + size = {"height": 448, "width": 448} + patch_size = 14 + dynamic_hd = 36 + image_mean = [0.5, 0.5, 0.5] + image_std = [0.5, 0.5, 0.5] + do_resize = True + do_rescale = True + do_normalize = True + do_convert_rgb = True + valid_kwargs = Phi4MultimodalImageProcessorKwargs + model_input_names = ["image_pixel_values", "image_sizes", "image_attention_mask"] + + def __init__(self, **kwargs: Unpack[Phi4MultimodalImageProcessorKwargs]): + super().__init__(**kwargs) + + def find_closest_aspect_ratio(self, aspect_ratio, target_ratios, width, height, image_size): + best_ratio_diff = float("inf") + best_ratio = (1, 1) + area = width * height + for ratio in target_ratios: + target_aspect_ratio = ratio[0] / ratio[1] + ratio_diff = abs(aspect_ratio - target_aspect_ratio) + if ratio_diff < best_ratio_diff: + best_ratio_diff = ratio_diff + best_ratio = ratio + elif ratio_diff == best_ratio_diff: + if area > 0.5 * image_size * image_size * ratio[0] * ratio[1]: + best_ratio = ratio + return best_ratio + + def dynamic_preprocess(self, image, image_size, patch_size, mask_size, max_num=36, min_num=1): + orig_height, orig_width = image.shape[-2:] + + w_crop_num = math.ceil(orig_width / float(image_size)) + h_crop_num = math.ceil(orig_height / float(image_size)) + if w_crop_num * h_crop_num > max_num: + aspect_ratio = orig_width / orig_height + + # calculate the existing image aspect ratio + target_ratios = { + (i, j) + for n in range(min_num, max_num + 1) + for i in range(1, n + 1) + for j in range(1, n + 1) + if i * j <= max_num and i * j >= min_num + } + target_ratios = sorted(target_ratios, key=lambda x: x[0] * x[1]) + + # find the closest aspect ratio to the target + target_aspect_ratio = self.find_closest_aspect_ratio( + aspect_ratio, target_ratios, orig_width, orig_height, image_size + ) + + # calculate the target width and height + target_width = image_size * target_aspect_ratio[0] + target_height = image_size * target_aspect_ratio[1] + else: + target_width = image_size * w_crop_num + target_height = image_size * h_crop_num + target_aspect_ratio = (w_crop_num, h_crop_num) + + # Calculate the ratio + ratio_width = target_width / orig_width + ratio_height = target_height / orig_height + if ratio_width < ratio_height: + new_size = (target_width, int(orig_height * ratio_width)) + padding_width = 0 + padding_height = target_height - int(orig_height * ratio_width) + else: + new_size = (int(orig_width * ratio_height), target_height) + padding_width = target_width - int(orig_width * ratio_height) + padding_height = 0 + + attention_mask = torch.ones((int(mask_size * target_aspect_ratio[1]), int(mask_size * target_aspect_ratio[0]))) + if padding_width >= patch_size: + attention_mask[:, -math.floor(padding_width / patch_size) :] = 0 + if padding_height >= patch_size: + attention_mask[-math.floor(padding_height / patch_size) :, :] = 0 + + if min(new_size[1], target_height) < 10 or min(new_size[0], target_width) < 10: + raise ValueError(f"the aspect ratio is very extreme {new_size}") + + image = tvF.resize(image, [new_size[1], new_size[0]]) + resized_img = tvF.pad(image, [0, 0, padding_width, padding_height], fill=[255, 255, 255]) + + return resized_img, attention_mask + + def pad_to_max_num_crops(self, images, max_crops=5): + """ + images: B x 3 x H x W, B<=max_crops + """ + B, _, H, W = images.shape + if max_crops > B: + pad = torch.zeros(max_crops - B, 3, H, W, dtype=images.dtype, device=images.device) + images = torch.cat([images, pad], dim=0) + return images + + def pad_mask_to_max_num_crops(self, masks, max_crops=5): + B, H, W = masks.shape + if max_crops > B: + pad = torch.ones(max_crops - B, H, W, dtype=masks.dtype, device=masks.device) + masks = torch.cat([masks, pad], dim=0) + return masks + + @auto_docstring + def preprocess( + self, + images: ImageInput, + **kwargs: Unpack[Phi4MultimodalImageProcessorKwargs], + ) -> BatchFeature: + return super().preprocess(images, **kwargs) + + def _preprocess( + self, + images: list["torch.Tensor"], + size: SizeDict, + interpolation: Optional["tvF.InterpolationMode"], + patch_size: int, + dynamic_hd: int, + do_rescale: bool, + rescale_factor: float | None, + do_normalize: bool, + image_mean: float | list[float] | None = None, + image_std: float | list[float] | None = None, + return_tensors: str | TensorType | None = None, + **kwargs, + ): + if size.height != size.width: + raise ValueError("Phi4MultimodalFastImageProcessor only supports square sizes.") + mask_size = size.height // patch_size + images_transformed = [] + masks_transformed = [] + images_tokens = [] + image_sizes = [] + for image in images: + resized_image, attention_mask = self.dynamic_preprocess( + image, size.height, patch_size, mask_size, max_num=dynamic_hd + ) + processed_image = self.rescale_and_normalize( + resized_image, do_rescale, rescale_factor, do_normalize, image_mean, image_std + ) + global_image = self.resize(processed_image, size, interpolation=interpolation, antialias=False) + height, width = processed_image.shape[-2:] + mask_height, mask_width = attention_mask.shape[-2:] + global_attention_mask = torch.ones((1, mask_size, mask_size)) + + hd_image_reshape = processed_image.reshape( + 1, 3, height // size.height, size.height, width // size.width, size.width + ) + hd_image_reshape = hd_image_reshape.permute(0, 2, 4, 1, 3, 5) + hd_image_reshape = hd_image_reshape.reshape(-1, 3, size.height, size.width).contiguous() + + attention_mask_reshape = attention_mask.reshape( + mask_height // mask_size, mask_size, mask_width // mask_size, mask_size + ) + attention_mask_reshape = attention_mask_reshape.transpose(1, 2) + attention_mask_reshape = attention_mask_reshape.reshape(-1, mask_size, mask_size).contiguous() + + downsample_attention_mask = attention_mask_reshape[:, 0::2, 0::2] + downsample_attention_mask = downsample_attention_mask.reshape( + mask_height // mask_size, + mask_width // mask_size, + mask_size // 2 + mask_size % 2, + mask_size // 2 + mask_size % 2, + ) + downsample_attention_mask = downsample_attention_mask.transpose(1, 2) + downsample_attention_mask = downsample_attention_mask.reshape( + downsample_attention_mask.size(0) * downsample_attention_mask.size(1), + downsample_attention_mask.size(2) * downsample_attention_mask.size(3), + ) + + num_img_tokens = ( + 256 + + 1 + + int(downsample_attention_mask.sum().item()) + + int(downsample_attention_mask[:, 0].sum().item()) + + 16 + ) + + hd_image_reshape = torch.cat([global_image.unsqueeze(0), hd_image_reshape], dim=0) + hd_attention_mask_reshape = torch.cat([global_attention_mask, attention_mask_reshape], dim=0) + + images_transformed.append(hd_image_reshape) + masks_transformed.append(hd_attention_mask_reshape) + images_tokens.append(num_img_tokens) + image_sizes.append([height, width]) + max_crops = hd_image_reshape.size(0) + max_crops = max(img.size(0) for img in images_transformed) + images_transformed = [self.pad_to_max_num_crops(im, max_crops) for im in images_transformed] + images_transformed = torch.stack(images_transformed, dim=0) + masks_transformed = [self.pad_mask_to_max_num_crops(mask, max_crops) for mask in masks_transformed] + masks_transformed = torch.stack(masks_transformed, dim=0) + image_sizes = torch.tensor(image_sizes, dtype=torch.long) + + data = { + "image_pixel_values": images_transformed, + "image_sizes": image_sizes, + "image_attention_mask": masks_transformed, + "num_img_tokens": images_tokens, + } + + return BatchFeature(data=data, tensor_type=return_tensors) + + +__all__ = ["Phi4MultimodalImageProcessorFast"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/phi4_multimodal/modeling_phi4_multimodal.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/phi4_multimodal/modeling_phi4_multimodal.py new file mode 100644 index 0000000000000000000000000000000000000000..a62f70d5ea0f6f81faae45499f48aecb20cf0b18 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/phi4_multimodal/modeling_phi4_multimodal.py @@ -0,0 +1,1782 @@ +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# This file was automatically generated from src/transformers/models/phi4_multimodal/modular_phi4_multimodal.py. +# Do NOT edit this file manually as any edits will be overwritten by the generation of +# the file from the modular. If any change should be done, please apply the change to the +# modular_phi4_multimodal.py file directly. One of our CI enforces this. +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# Copyright 2025 Microsoft and the HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import math +from collections.abc import Callable +from typing import Optional + +import numpy as np +import torch +import torch.nn.functional as F +from torch import nn + +from ... import initialization as init +from ...activations import ACT2FN +from ...cache_utils import Cache, DynamicCache +from ...generation import GenerationMixin +from ...integrations import use_kernel_forward_from_hub +from ...masking_utils import create_bidirectional_mask, create_causal_mask, create_sliding_window_causal_mask +from ...modeling_flash_attention_utils import FlashAttentionKwargs +from ...modeling_layers import GradientCheckpointingLayer +from ...modeling_outputs import ( + BaseModelOutput, + BaseModelOutputWithPast, + BaseModelOutputWithPooling, + CausalLMOutputWithPast, +) +from ...modeling_rope_utils import ROPE_INIT_FUNCTIONS, dynamic_rope_update +from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel +from ...processing_utils import Unpack +from ...utils import auto_docstring, can_return_tuple, torch_int +from ...utils.generic import TransformersKwargs, maybe_autocast, merge_with_config_defaults +from ...utils.output_capturing import capture_outputs +from .configuration_phi4_multimodal import Phi4MultimodalAudioConfig, Phi4MultimodalConfig, Phi4MultimodalVisionConfig + + +class Phi4MultimodalVisionMLP(nn.Module): + def __init__(self, config): + super().__init__() + self.config = config + self.activation_fn = ACT2FN[config.hidden_act] + self.fc1 = nn.Linear(config.hidden_size, config.intermediate_size) + self.fc2 = nn.Linear(config.intermediate_size, config.hidden_size) + + def forward(self, hidden_states: torch.Tensor) -> torch.Tensor: + hidden_states = self.fc1(hidden_states) + hidden_states = self.activation_fn(hidden_states) + hidden_states = self.fc2(hidden_states) + return hidden_states + + +def simple_eager_attention_forward( + module: nn.Module, + query_states: torch.Tensor, + key_states: torch.Tensor, + value_states: torch.Tensor, + attention_mask: torch.Tensor | None, + scaling: float, + dropout: float = 0.0, + **kwargs: Unpack[TransformersKwargs], +): + attn_weights = torch.matmul(query_states, key_states.transpose(2, 3)) * scaling + if attention_mask is not None: + attn_weights = attn_weights + attention_mask + + attn_weights = nn.functional.softmax(attn_weights, dim=-1, dtype=torch.float32).to(query_states.dtype) + attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training) + attn_output = torch.matmul(attn_weights, value_states) + attn_output = attn_output.transpose(1, 2).contiguous() + + return attn_output, attn_weights + + +class Phi4MultimodalVisionAttention(nn.Module): + def __init__(self, config: Phi4MultimodalVisionConfig): + super().__init__() + self.config = config + self.embed_dim = config.hidden_size + self.num_heads = config.num_attention_heads + self.head_dim = self.embed_dim // self.num_heads + self.scaling = self.head_dim**-0.5 + self.is_causal = True + self.attention_dropout = config.attention_dropout + + self.k_proj = nn.Linear(config.hidden_size, config.hidden_size) + self.v_proj = nn.Linear(config.hidden_size, config.hidden_size) + self.q_proj = nn.Linear(config.hidden_size, config.hidden_size) + self.out_proj = nn.Linear(config.hidden_size, config.hidden_size) + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor, torch.Tensor | None]: + """Input shape: Batch x Time x Channel""" + input_shape = hidden_states.shape[:-1] + hidden_shape = (*input_shape, -1, self.head_dim) + + query_states = self.q_proj(hidden_states).view(hidden_shape).transpose(1, 2) + key_states = self.k_proj(hidden_states).view(hidden_shape).transpose(1, 2) + value_states = self.v_proj(hidden_states).view(hidden_shape).transpose(1, 2) + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, simple_eager_attention_forward + ) + + attn_output, attn_weights = attention_interface( + self, + query_states, + key_states, + value_states, + attention_mask, + dropout=0.0 if not self.training else self.attention_dropout, + scaling=self.scaling, + **kwargs, + ) + + attn_output = attn_output.reshape(*input_shape, -1) + attn_output = self.out_proj(attn_output) + return attn_output, attn_weights + + +class Phi4MultimodalVisionEncoderLayer(GradientCheckpointingLayer): + def __init__(self, config: Phi4MultimodalVisionConfig): + super().__init__() + self.embed_dim = config.hidden_size + self.layer_norm1 = nn.LayerNorm(self.embed_dim, eps=config.layer_norm_eps) + self.self_attn = Phi4MultimodalVisionAttention(config) + self.layer_norm2 = nn.LayerNorm(self.embed_dim, eps=config.layer_norm_eps) + self.mlp = Phi4MultimodalVisionMLP(config) + + @auto_docstring + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.Tensor, + **kwargs: Unpack[TransformersKwargs], + ) -> torch.FloatTensor: + residual = hidden_states + + hidden_states = self.layer_norm1(hidden_states) + hidden_states, _ = self.self_attn( + hidden_states=hidden_states, + attention_mask=attention_mask, + **kwargs, + ) + hidden_states = residual + hidden_states + + residual = hidden_states + hidden_states = self.layer_norm2(hidden_states) + hidden_states = self.mlp(hidden_states) + hidden_states = residual + hidden_states + + return hidden_states + + +class Phi4MultimodalVisionEncoder(nn.Module): + """ + Transformer encoder consisting of `config.num_hidden_layers` self attention layers. Each layer is a + [`Phi4MultimodalVisionEncoderLayer`]. + + Args: + config: Phi4MultimodalVisionConfig + """ + + def __init__(self, config: Phi4MultimodalVisionConfig): + super().__init__() + self.config = config + self.layers = nn.ModuleList( + [Phi4MultimodalVisionEncoderLayer(config) for _ in range(config.num_hidden_layers)] + ) + self.gradient_checkpointing = False + + # Ignore copy + @auto_docstring + def forward( + self, + inputs_embeds, + attention_mask: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> BaseModelOutput: + hidden_states = inputs_embeds + for encoder_layer in self.layers: + hidden_states = encoder_layer( + hidden_states, + attention_mask, + **kwargs, + ) + + return BaseModelOutput(last_hidden_state=hidden_states) + + +@auto_docstring +class Phi4MultimodalVisionPreTrainedModel(PreTrainedModel): + config: Phi4MultimodalVisionConfig + base_model_prefix = "phi4_vision" + input_modalities = ("image",) + supports_gradient_checkpointing = True + + _no_split_modules = ["Phi4MultimodalVisionEncoderLayer"] + _supports_flash_attn = True + _supports_sdpa = True + _supports_flex_attn = True + _supports_attention_backend = True + + _can_record_outputs = { + "hidden_states": Phi4MultimodalVisionEncoderLayer, + "attentions": Phi4MultimodalVisionAttention, + } + + @torch.no_grad() + def _init_weights(self, module): + """Initialize the weights""" + if isinstance(module, Phi4MultimodalVisionEmbeddings): + width = ( + self.config.hidden_size + if isinstance(self.config, Phi4MultimodalVisionConfig) + else self.config.hidden_size + ) + init.normal_(module.position_embedding.weight, std=1 / np.sqrt(width)) + elif isinstance(module, nn.Embedding): + init.default_flax_embed_init_(module.weight) + elif isinstance(module, Phi4MultimodalVisionAttention): + init.normal_(module.q_proj.weight) + init.normal_(module.k_proj.weight) + init.normal_(module.v_proj.weight) + init.normal_(module.out_proj.weight) + init.zeros_(module.q_proj.bias) + init.zeros_(module.k_proj.bias) + init.zeros_(module.v_proj.bias) + init.zeros_(module.out_proj.bias) + elif isinstance(module, Phi4MultimodalVisionMLP): + init.normal_(module.fc1.weight) + init.normal_(module.fc2.weight) + init.normal_(module.fc1.bias, std=1e-6) + init.normal_(module.fc2.bias, std=1e-6) + elif isinstance(module, Phi4MultimodalVisionMultiheadAttentionPoolingHead): + init.normal_(module.probe) + init.normal_(module.attention.in_proj_weight) + init.zeros_(module.attention.in_proj_bias) + elif isinstance(module, (nn.Linear, nn.Conv2d)): + init.lecun_normal_(module.weight) + if module.bias is not None: + init.zeros_(module.bias) + elif isinstance(module, nn.LayerNorm): + init.zeros_(module.bias) + init.ones_(module.weight) + + +class Phi4MultimodalVisionEmbeddings(nn.Module): + def __init__(self, config: Phi4MultimodalVisionConfig): + super().__init__() + self.config = config + self.patch_size = config.patch_size + self.num_patches_per_side = config.image_size // self.patch_size + + self.patch_embedding = nn.Conv2d( + in_channels=config.num_channels, + out_channels=config.hidden_size, + kernel_size=self.patch_size, + stride=self.patch_size, + padding="valid", + ) + self.position_embedding = nn.Embedding(self.num_patches_per_side**2, config.hidden_size) + + def interpolate_pos_encoding(self, embeddings: torch.Tensor, height: int, width: int) -> torch.Tensor: + """ + This method allows to interpolate the pre-trained position encodings, to be able to use the model on higher resolution + images. This method is also adapted to support torch.jit tracing and no class embeddings. + + Adapted from: + - https://github.com/facebookresearch/dino/blob/de9ee3df6cf39fac952ab558447af1fa1365362a/vision_transformer.py#L174-L194, and + - https://github.com/facebookresearch/dinov2/blob/e1277af2ba9496fbadf7aec6eba56e8d882d1e35/dinov2/models/vision_transformer.py#L179-L211 + """ + + num_patches = embeddings.shape[1] + num_positions = self.position_embedding.weight.shape[0] + + # always interpolate when tracing to ensure the exported model works for dynamic input shapes + if not torch.jit.is_tracing() and num_patches == num_positions and height == width: + return self.position_embedding(self.position_ids) + + patch_pos_embed = self.position_embedding.weight.unsqueeze(0) + + dim = embeddings.shape[-1] + + new_height = height // self.patch_size + new_width = width // self.patch_size + + sqrt_num_positions = torch_int(num_positions**0.5) + patch_pos_embed = patch_pos_embed.reshape(1, sqrt_num_positions, sqrt_num_positions, dim) + patch_pos_embed = patch_pos_embed.permute(0, 3, 1, 2) + + patch_pos_embed = nn.functional.interpolate( + patch_pos_embed, + size=(new_height, new_width), + mode="bicubic", + align_corners=False, + ) + + patch_pos_embed = patch_pos_embed.permute(0, 2, 3, 1).view(1, -1, dim) + return patch_pos_embed + + def forward(self, pixel_values: torch.FloatTensor, patch_attention_mask: torch.BoolTensor) -> torch.Tensor: + batch_size, _, max_im_h, max_im_w = pixel_values.shape + + patch_embeds = self.patch_embedding(pixel_values) + embeddings = patch_embeds.flatten(2).transpose(1, 2) + + max_nb_patches_h, max_nb_patches_w = max_im_h // self.patch_size, max_im_w // self.patch_size + boundaries = torch.arange( + 1 / self.num_patches_per_side, 1.0, 1 / self.num_patches_per_side, device=pixel_values.device + ) + position_ids = torch.full( + size=(batch_size, max_nb_patches_h * max_nb_patches_w), fill_value=0, device=pixel_values.device + ) + + nb_patches_h = patch_attention_mask[:, :, 0].sum(dim=1) # (batch_size,) + nb_patches_w = patch_attention_mask[:, 0, :].sum(dim=1) # (batch_size,) + + step_h = 1.0 / nb_patches_h # (batch_size,) + step_w = 1.0 / nb_patches_w # (batch_size,) + + max_patches_h = patch_attention_mask.size(1) + max_patches_w = patch_attention_mask.size(2) + h_indices = torch.arange(max_patches_h, device=position_ids.device, dtype=torch.float32) + w_indices = torch.arange(max_patches_w, device=position_ids.device, dtype=torch.float32) + + fractional_coords_h = h_indices[None, :] * step_h[:, None] + fractional_coords_w = w_indices[None, :] * step_w[:, None] + + fractional_coords_h = torch.clamp(fractional_coords_h, max=(1.0 - 1e-6)) + fractional_coords_w = torch.clamp(fractional_coords_w, max=(1.0 - 1e-6)) + + fractional_coords_h = fractional_coords_h.to(pixel_values.dtype) + fractional_coords_w = fractional_coords_w.to(pixel_values.dtype) + + bucket_coords_h = torch.bucketize(fractional_coords_h, boundaries, right=True) + bucket_coords_w = torch.bucketize(fractional_coords_w, boundaries, right=True) + + pos_ids = bucket_coords_h[:, :, None] * self.num_patches_per_side + bucket_coords_w[:, None, :] + pos_ids = pos_ids.reshape(batch_size, -1) + + position_ids[patch_attention_mask.view(batch_size, -1)] = pos_ids[patch_attention_mask.view(batch_size, -1)] + + embeddings = embeddings + self.position_embedding(position_ids) + return embeddings + + +class Phi4MultimodalVisionMultiheadAttentionPoolingHead(nn.Module): + """Multihead Attention Pooling.""" + + def __init__(self, config: Phi4MultimodalVisionConfig): + super().__init__() + + self.probe = nn.Parameter(torch.randn(1, 1, config.hidden_size)) + self.attention = torch.nn.MultiheadAttention(config.hidden_size, config.num_attention_heads, batch_first=True) + self.layernorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps) + self.mlp = Phi4MultimodalVisionMLP(config) + + def forward(self, hidden_state, attention_mask): + batch_size = hidden_state.shape[0] + probe = self.probe.repeat(batch_size, 1, 1) + + hidden_state = self.attention( + query=probe, key=hidden_state, value=hidden_state, key_padding_mask=~attention_mask + )[0] + + residual = hidden_state + hidden_state = self.layernorm(hidden_state) + hidden_state = residual + self.mlp(hidden_state) + + return hidden_state[:, 0] + + +class Phi4MultimodalVisionModel(Phi4MultimodalVisionPreTrainedModel): + config: Phi4MultimodalVisionConfig + main_input_name = "pixel_values" + + def __init__(self, config: Phi4MultimodalVisionConfig): + super().__init__(config) + self.config = config + + self.embeddings = Phi4MultimodalVisionEmbeddings(config) + self.encoder = Phi4MultimodalVisionEncoder(config) + self.post_layernorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps) + self.head = Phi4MultimodalVisionMultiheadAttentionPoolingHead(config) + + # Initialize weights and apply final processing + self.post_init() + + def get_input_embeddings(self) -> nn.Module: + return self.embeddings.patch_embedding + + @merge_with_config_defaults + @capture_outputs(tie_last_hidden_states=False) + def forward( + self, + pixel_values, + patch_attention_mask: torch.BoolTensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple | BaseModelOutputWithPooling: + batch_size = pixel_values.size(0) + if patch_attention_mask is None: + patch_attention_mask = torch.ones( + size=( + batch_size, + pixel_values.size(2) // self.config.patch_size, + pixel_values.size(3) // self.config.patch_size, + ), + dtype=torch.bool, + device=pixel_values.device, + ) + + hidden_states = self.embeddings(pixel_values=pixel_values, patch_attention_mask=patch_attention_mask) + + patch_attention_mask = patch_attention_mask.view(batch_size, -1) + attention_mask = create_bidirectional_mask( + config=self.config, + inputs_embeds=hidden_states, + attention_mask=patch_attention_mask, + ) + + encoder_outputs: BaseModelOutput = self.encoder( + inputs_embeds=hidden_states, + attention_mask=attention_mask, + **kwargs, + ) + + last_hidden_state = encoder_outputs.last_hidden_state + last_hidden_state = self.post_layernorm(last_hidden_state) + + pooled_output = self.head( + hidden_state=last_hidden_state, + attention_mask=patch_attention_mask, + ) + + return BaseModelOutputWithPooling( + last_hidden_state=last_hidden_state, + pooler_output=pooled_output, + ) + + +class Phi4MultimodalImageEmbedding(nn.Module): + """Image embedding.""" + + def __init__(self, config: Phi4MultimodalConfig): + super().__init__() + self.config = config + self.layer_idx = config.vision_config.feature_layer + self.crop_size = config.vision_config.crop_size + self.image_dim_out = config.vision_config.hidden_size + + n_patches = config.vision_config.image_size // config.vision_config.patch_size + if n_patches % 2 != 0: + self.img_processor_padding = nn.ReflectionPad2d((0, 1, 0, 1)) + n_patches += 1 + self.num_img_tokens = (n_patches // 2) ** 2 + + self.drop = nn.Dropout(config.embd_pdrop) + self.img_processor = Phi4MultimodalVisionModel._from_config(config.vision_config) + self.image_token_compression = nn.AvgPool2d(kernel_size=2, stride=2) + self.img_projection_up = nn.Linear(self.image_dim_out, config.hidden_size) + self.img_projection_down = nn.Linear(config.hidden_size, config.hidden_size) + self.global_img_feature_extensor = nn.Parameter(torch.zeros([1, 1, self.image_dim_out])) + self.sub_img_feature_extensor = nn.Parameter(torch.zeros([1, 1, 1, self.image_dim_out])) + + def get_img_features(self, img_embeds: torch.FloatTensor, attention_mask=None) -> torch.FloatTensor: + img_processor_output = self.img_processor( + img_embeds, patch_attention_mask=attention_mask, output_hidden_states=True + ) + img_feature = img_processor_output.hidden_states[self.layer_idx] + + patch_feature = img_feature + # reshape to 2D tensor + width = int(math.sqrt(patch_feature.size(1))) + patch_feature = patch_feature.view(-1, width, width, patch_feature.size(-1)) + # convert to NCHW + patch_feature = patch_feature.permute(0, 3, 1, 2) + if getattr(self, "img_processor_padding", None) is not None: + patch_feature = self.img_processor_padding(patch_feature) + patch_feature = self.image_token_compression(patch_feature) + # convert to NHWC + patch_feature = patch_feature.permute(0, 2, 3, 1) + patch_feature = patch_feature.view(-1, patch_feature.size(1) * patch_feature.size(2), patch_feature.size(-1)) + return patch_feature + + def forward( + self, + input_ids: torch.LongTensor, + inputs_embeds: torch.Tensor, + image_pixel_values: torch.FloatTensor, + image_sizes: torch.Tensor | None = None, + image_attention_mask: torch.Tensor | None = None, + ) -> torch.FloatTensor: + image_pixel_values = image_pixel_values.to(self.img_processor.embeddings.patch_embedding.weight.dtype) + + target_device = self.img_projection_up.bias.device + target_dtype = self.img_projection_up.bias.dtype + + batch_size = image_pixel_values.shape[0] + + img_features = self.get_img_features( + image_pixel_values.flatten(0, 1), + attention_mask=image_attention_mask.flatten(0, 1).to(dtype=bool, device=target_device), + ) + base_feat_size = int(np.sqrt(img_features.shape[1])) + img_features = img_features.view(batch_size, -1, base_feat_size**2, self.image_dim_out) + image_sizes = image_sizes.view(-1, 2) + + output_imgs = [] + for idx in range(batch_size): + height, width = image_sizes[idx] + height_ratio = height // self.crop_size + width_ratio = width // self.crop_size + area_ratio = height_ratio * width_ratio + + global_img = img_features[idx, :1] + global_img = global_img.reshape(1, base_feat_size, base_feat_size, self.image_dim_out).contiguous() + temporary_extensor = self.sub_img_feature_extensor.repeat(1, base_feat_size, 1, 1) + global_img = torch.cat([global_img, temporary_extensor], dim=2).reshape(1, -1, self.image_dim_out) + + sub_img = img_features[idx, 1:] + sub_img = sub_img[:area_ratio] + sub_img = ( + sub_img.reshape(height_ratio, width_ratio, base_feat_size, base_feat_size, self.image_dim_out) + .transpose(1, 2) + .reshape(1, height_ratio * base_feat_size, width_ratio * base_feat_size, self.image_dim_out) + .contiguous() + ) + + if image_attention_mask is not None: + reshaped_image_attention_mask = ( + image_attention_mask[idx, 1 : area_ratio + 1, 0::2, 0::2] + .reshape(height_ratio, width_ratio, base_feat_size, base_feat_size) + .transpose(1, 2) + .reshape(1, height_ratio * base_feat_size, width_ratio * base_feat_size) + ) + useful_height = int(reshaped_image_attention_mask[0, :, 0].sum().item()) + useful_width = int(reshaped_image_attention_mask[0, 0, :].sum().item()) + sub_img = sub_img[:, :useful_height, :useful_width] + temporary_extensor = self.sub_img_feature_extensor.repeat(1, useful_height, 1, 1) + else: + temporary_extensor = self.sub_img_feature_extensor.repeat(1, height_ratio * base_feat_size, 1, 1) + + sub_img = torch.cat([sub_img, temporary_extensor], dim=2).reshape(1, -1, self.image_dim_out) + + # Merge global and sub + output_imgs.append(torch.cat([sub_img, self.global_img_feature_extensor, global_img], dim=1)) + + img_set_tensor = [] + for output_img in output_imgs: + output_img = output_img.to(device=target_device, dtype=target_dtype) + img_feature_proj = self.img_projection_up(output_img) + img_feature_proj = nn.functional.gelu(img_feature_proj) + img_feature_proj = self.img_projection_down(img_feature_proj) + img_set_tensor.append(img_feature_proj) + + merged_img_set_tensor = torch.cat(img_set_tensor, dim=1).squeeze(0) + merged_img_set_tensor = merged_img_set_tensor.to(dtype=inputs_embeds.dtype, device=inputs_embeds.device) + + with torch.no_grad(): + positions_tuple = torch.nonzero(input_ids == self.config.vision_config.image_token_id, as_tuple=True) + + # Temporarily disable autocast to avoid issue on bf16 tensors + # Ref: https://github.com/pytorch/pytorch/issues/132715 + with maybe_autocast(device_type=inputs_embeds.device.type, enabled=False): + image_embeds = inputs_embeds.index_put( + indices=positions_tuple, values=merged_img_set_tensor, accumulate=False + ) + + image_embeds = self.drop(image_embeds) + + return image_embeds + + +########################################################## AUDIO ############################################# + + +class Phi4MultimodalAudioMLP(nn.Module): + def __init__(self, config: Phi4MultimodalAudioConfig): + super().__init__() + self.layer_norm = nn.LayerNorm(config.hidden_size) + self.act_fn = ACT2FN[config.activation] + self.gate_up_proj = nn.Linear(config.hidden_size, config.intermediate_size * 2) + self.down_proj = nn.Linear(config.intermediate_size, config.hidden_size) + self.dropout = nn.Dropout(config.dropout_rate) + + def forward(self, hidden_states): + hidden_states = self.layer_norm(hidden_states) + up_states = self.gate_up_proj(hidden_states) + up_states, gate = up_states.chunk(2, dim=-1) + up_states = up_states * self.act_fn(gate) + up_states = self.dropout(up_states) + hidden_states = self.down_proj(up_states) + out = self.dropout(hidden_states) + + return out + + +class Phi4MultimodalAudioAttention(nn.Module): + def __init__(self, config: Phi4MultimodalAudioConfig): + super().__init__() + self.config = config + self.head_dim = getattr(config, "head_dim", config.hidden_size // config.num_attention_heads) + self.scaling = self.head_dim**-0.5 + self.attention_dropout = config.dropout_rate + self.is_causal = True + + self.q_proj = nn.Linear(config.hidden_size, config.num_attention_heads * self.head_dim, bias=True) + self.k_proj = nn.Linear(config.hidden_size, config.num_attention_heads * self.head_dim, bias=True) + self.v_proj = nn.Linear(config.hidden_size, config.num_attention_heads * self.head_dim, bias=True) + self.o_proj = nn.Linear(config.num_attention_heads * self.head_dim, config.hidden_size, bias=True) + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.Tensor, + **kwargs, + ): + input_shape = hidden_states.shape[:-1] + hidden_shape = (*input_shape, -1, self.head_dim) + + query_states = self.q_proj(hidden_states).view(hidden_shape).transpose(1, 2) + key_states = self.k_proj(hidden_states).view(hidden_shape).transpose(1, 2) + value_states = self.v_proj(hidden_states).view(hidden_shape).transpose(1, 2) + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, simple_eager_attention_forward + ) + + attn_output, _ = attention_interface( + self, + query_states, + key_states, + value_states, + attention_mask, + dropout=0.0 if not self.training else self.attention_dropout, + scaling=self.scaling, + **kwargs, + ) + + attn_output = attn_output.reshape(*input_shape, -1).contiguous() + attn_output = self.o_proj(attn_output) + return attn_output + + +class Phi4MultimodalAudioDepthWiseSeparableConv1d(nn.Module): + def __init__(self, config: Phi4MultimodalAudioConfig, padding: int = 0): + super().__init__() + self.dw_conv = nn.Conv1d( + config.hidden_size, + config.hidden_size * config.depthwise_multiplier, + config.kernel_size, + 1, + padding=padding, + groups=config.hidden_size, + ) + self.pw_conv = nn.Conv1d( + config.hidden_size * config.depthwise_multiplier, config.depthwise_separable_out_channel, 1, 1, 0 + ) + + def forward(self, hidden_states): + return self.pw_conv(self.dw_conv(hidden_states)) + + +class Phi4MultimodalAudioGluPointWiseConv(nn.Module): + def __init__(self, config: Phi4MultimodalAudioConfig): + super().__init__() + self.config = config + self.output_dim = config.ext_pw_out_channel + + self.ext_pw_conv_1d = nn.Conv1d(config.hidden_size, config.ext_pw_out_channel * 2, kernel_size=1, stride=1) + self.glu_act = ACT2FN[config.conv_glu_type] + self.b1 = nn.Parameter(torch.zeros(1, config.ext_pw_out_channel, 1)) + self.b2 = nn.Parameter(torch.zeros(1, config.ext_pw_out_channel, 1)) + + def forward(self, hidden_states): + # we assume the input always has the #channel (#dim) in the last dimension of the + # tensor, so need to switch the dimension first for 1D-Conv case + hidden_states = hidden_states.permute([0, 2, 1]) + hidden_states = self.ext_pw_conv_1d(hidden_states) + out = hidden_states[:, 0 : self.output_dim, :] + self.b1 + out = out * self.glu_act(hidden_states[:, self.output_dim : self.output_dim * 2, :] + self.b2) + return out.permute([0, 2, 1]) + + +class Phi4MultimodalAudioConvModule(nn.Module): + def __init__(self, config: Phi4MultimodalAudioConfig): + super().__init__() + self.config = config + self.kernel_size = config.kernel_size + + self.layer_norm = nn.LayerNorm(config.hidden_size) + self.glu = Phi4MultimodalAudioGluPointWiseConv(config) + self.dw_sep_conv_1d = Phi4MultimodalAudioDepthWiseSeparableConv1d(config, padding=config.kernel_size - 1) + self.act = ACT2FN[config.conv_activation] + self.ext_pw_conv_1d = nn.Conv1d(config.hidden_size, config.ext_pw_out_channel, kernel_size=1, stride=1) + self.dropout = nn.Dropout(config.dropout_rate) + + def forward(self, hidden_states: torch.Tensor): + hidden_states = self.glu(self.layer_norm(hidden_states)) + hidden_states = self.dw_sep_conv_1d(hidden_states.permute([0, 2, 1])) + + if self.kernel_size > 1: + hidden_states = hidden_states[:, :, : -(self.kernel_size - 1)] + + hidden_states = self.act(hidden_states) + hidden_states = self.ext_pw_conv_1d(hidden_states) + out = self.dropout(hidden_states.permute([0, 2, 1])) + return out + + +class Phi4MultimodalAudioConformerEncoderLayer(nn.Module): + def __init__(self, config: Phi4MultimodalAudioConfig): + super().__init__() + + self.feed_forward_in = Phi4MultimodalAudioMLP(config) + self.self_attn = Phi4MultimodalAudioAttention(config) + self.conv = Phi4MultimodalAudioConvModule(config) + self.feed_forward_out = Phi4MultimodalAudioMLP(config) + self.layer_norm_att = nn.LayerNorm(config.hidden_size) + self.layer_norm = nn.LayerNorm(config.hidden_size) + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.Tensor, + ): + residual = hidden_states + 0.5 * self.feed_forward_in(hidden_states) + hidden_states = self.layer_norm_att(residual) + + hidden_states = residual + self.self_attn(hidden_states, attention_mask) + hidden_states = hidden_states + self.conv(hidden_states) + hidden_states = hidden_states + 0.5 * self.feed_forward_out(hidden_states) + + out = self.layer_norm(hidden_states) + + return out + + +class Phi4MultimodalAudioNemoConvSubsampling(torch.nn.Module): + def __init__(self, config: Phi4MultimodalAudioConfig): + super().__init__() + self.subsampling_factor = config.time_reduction + self.sampling_num = int(math.log2(self.subsampling_factor)) + self.act_fn = ACT2FN[config.nemo_activation] + conv_channels = config.nemo_conv_channels + + layers = [ + nn.Conv2d(1, conv_channels, kernel_size=3, stride=2, padding=1), + self.act_fn, + ] + for _ in range(self.sampling_num - 1): + layers.extend( + [ + nn.Conv2d(conv_channels, conv_channels, kernel_size=3, stride=2, padding=1, groups=conv_channels), + nn.Conv2d(conv_channels, conv_channels, kernel_size=1, stride=1, padding=0, groups=1), + self.act_fn, + ] + ) + + # Aggregate the layers + self.conv = torch.nn.Sequential(*layers) + self.out = torch.nn.Linear(conv_channels * config.nemo_final_size, config.hidden_size) + + def forward(self, hidden_states: torch.Tensor, mask: torch.Tensor | None): + # Unsqueeze Channel Axis + hidden_states = hidden_states.unsqueeze(1) + hidden_states = self.conv(hidden_states) + + # Flatten Channel and Frequency Axes + b, _, t, _ = hidden_states.size() + hidden_states = self.out(hidden_states.transpose(1, 2).reshape(b, t, -1)) + + if mask is None: + return hidden_states, None + + max_audio_length = hidden_states.shape[1] + feature_lens = mask.sum(1) + padding_length = torch.ceil(feature_lens / self.subsampling_factor) + arange_ = torch.arange(0, max_audio_length, device=hidden_states.device) + pad_mask = arange_.expand(padding_length.size(0), -1) < padding_length.unsqueeze(1) + return hidden_states, pad_mask.unsqueeze(1) + + +class Phi4MultimodalAudioRelativeAttentionBias(nn.Module): + def __init__(self, config: Phi4MultimodalAudioConfig): + super().__init__() + + self.max_distance = config.bias_max_distance + self.symmetric = config.bias_symmetric + self.num_buckets = self.max_distance + if not config.bias_symmetric: + self.num_buckets *= 2 + self.bias_values = nn.Embedding(self.num_buckets, config.num_attention_heads) + + def forward(self, x): + # instantiate bias compatible with shape of x + max_pos = x.size(1) + context_position = torch.arange(max_pos, device=x.device, dtype=torch.long)[:, None] + memory_position = torch.arange(max_pos, device=x.device, dtype=torch.long)[None, :] + relative_position = memory_position - context_position + # clipping to a maximum distance using ops that play well with ONNX export + relative_position = relative_position.masked_fill(relative_position < -self.max_distance, -self.max_distance) + relative_position = relative_position.masked_fill( + relative_position > self.max_distance - 1, self.max_distance - 1 + ) + + # mapping from relative position to index in the bias parameter + bias_idx = relative_position + bias_idx = bias_idx.abs() if self.symmetric else bias_idx + self.num_buckets // 2 + + att_bias = self.bias_values(bias_idx) + att_bias = att_bias.permute(2, 0, 1).unsqueeze(0) + + return att_bias + + +class Phi4MultimodalAudioMeanVarianceNormLayer(nn.Module): + def __init__(self, config: Phi4MultimodalAudioConfig): + super().__init__() + self.register_buffer("global_mean", torch.zeros(config.input_size)) + self.register_buffer("global_invstd", torch.ones(config.input_size)) + + def forward(self, x): + return (x - self.global_mean) * self.global_invstd + + +@auto_docstring +class Phi4MultimodalAudioPreTrainedModel(PreTrainedModel): + config: Phi4MultimodalAudioConfig + input_modalities = "audio" + supports_gradient_checkpointing = True + _no_split_modules = ["Phi4MultimodalAudioConformerEncoderLayer"] + _supports_flash_attn = True + _supports_sdpa = True + _supports_flex_attn = True + + @torch.no_grad() + def _init_weights(self, module): + super()._init_weights(module) + if isinstance(module, Phi4MultimodalAudioGluPointWiseConv): + init.zeros_(module.b1) + init.zeros_(module.b2) + elif isinstance(module, Phi4MultimodalAudioMeanVarianceNormLayer): + init.zeros_(module.global_mean) + init.ones_(module.global_invstd) + + +def unfold_tensor(tensor, max_seq_len): + """ + For a given tensor with shape of (N, T, D), if sequence length T is longer than max_seq_len, + this function unfold it to a (NT', max_seq_len, D) where T' is T // max_seq_len. + Args: + tensor: N, T, D + """ + _, _, D = tensor.shape + tensor = tensor.transpose(-1, -2) + # N x D x 1 x T => N x (D x max_seq_len) x T' + tensor = F.unfold(tensor[..., None, :], kernel_size=(1, max_seq_len), stride=(1, max_seq_len)) + + new_bsz, _, slen = tensor.shape + tensor = tensor.view(new_bsz, -1, max_seq_len, slen) + tensor = tensor.permute(0, 3, 2, 1) + tensor = tensor.view(-1, max_seq_len, D).contiguous() + return tensor + + +def adaptive_enc_mask(x_len, chunk_start_idx, left_window=0, right_window=0): + """ + The function is very important for Transformer Transducer Streaming mode + Args: + xs_len (int): sequence length + chunk_start_idx (list): first idx of each chunk, such as [0,18,36,48]. It also supports adaptive chunk size [0,10,15,45] + left_window (int): how many left chunks can be seen + right_window (int): how many right chunks can be seen. It is used for chunk overlap model. + Returns: + mask (torch.Tensor): a mask tensor for streaming model + """ + chunk_start_idx = torch.Tensor(chunk_start_idx).long() + start_pad = torch.nn.functional.pad( + chunk_start_idx, (1, 0) + ) # append 0 to the beginning, so it becomes [0, 0, 18, 36, 48] + end_pad = torch.nn.functional.pad( + chunk_start_idx, (0, 1), value=x_len + ) # append x_len to the end, so it becomes [0,18,36,48, x_len] + seq_range = torch.arange(0, x_len).unsqueeze(-1) + idx = ((seq_range < end_pad) & (seq_range >= start_pad)).nonzero()[:, 1] + seq_range_expand = torch.arange(0, x_len).unsqueeze(0).expand(x_len, -1) + idx_left = idx - left_window + idx_left[idx_left < 0] = 0 + boundary_left = start_pad[idx_left] + mask_left = seq_range_expand >= boundary_left.unsqueeze(-1) + idx_right = idx + right_window + idx_right[idx_right > len(chunk_start_idx)] = len(chunk_start_idx) + boundary_right = end_pad[idx_right] + mask_right = seq_range_expand < boundary_right.unsqueeze(-1) + return mask_left & mask_right + + +class Phi4MultimodalAudioModel(Phi4MultimodalAudioPreTrainedModel): + def __init__(self, config: Phi4MultimodalAudioConfig): + super().__init__(config) + self.config = config + + self.encoder_embedding = Phi4MultimodalAudioMeanVarianceNormLayer(config) + self.embed = Phi4MultimodalAudioNemoConvSubsampling(config) + self.relative_attention_bias_layer = Phi4MultimodalAudioRelativeAttentionBias(config) + self.encoders = nn.ModuleList( + [Phi4MultimodalAudioConformerEncoderLayer(config) for _ in range(config.num_blocks)] + ) + self.gradient_checkpointing = False + + # Initialize weights and apply final processing + self.post_init() + + def _streaming_mask(self, seq_len, batch_size, chunk_size, left_chunk): + # Create mask matrix for streaming + # S stores start index. if chunksize is 18, s is [0,18,36,....] + chunk_start_idx = np.arange(0, seq_len, chunk_size) + # avoid randomness when run evaluation or decoding + if self.training and np.random.rand() > 0.5: + # Either first or last chunk is not complete. + # If only the last one is not complete, EOS is not effective + chunk_start_idx = seq_len - chunk_start_idx + chunk_start_idx = chunk_start_idx[::-1] + chunk_start_idx = chunk_start_idx[:-1] + chunk_start_idx = np.insert(chunk_start_idx, 0, 0) + + enc_streaming_mask = ( + adaptive_enc_mask(seq_len, chunk_start_idx, left_window=left_chunk) + .unsqueeze(0) + .expand([batch_size, -1, -1]) + ) + return enc_streaming_mask + + def forward_embeddings(self, hidden_states, masks): + """Forwarding the inputs through the top embedding layers""" + seq_len = math.ceil(hidden_states.shape[1] / self.config.time_reduction) + if seq_len <= 0: + raise ValueError( + f"The sequence length after time reduction is invalid: {seq_len}. Your input feature is too short." + ) + + batch_size = hidden_states.shape[0] + + enc_streaming_mask = self._streaming_mask(seq_len, batch_size, self.config.chunk_size, self.config.left_chunk) + enc_streaming_mask = enc_streaming_mask.to(hidden_states.device) + + hidden_states, masks = self.embed(hidden_states, masks) + + streaming_mask = enc_streaming_mask + if streaming_mask is not None and masks is not None: + hs_mask = masks & streaming_mask + elif masks is not None: + hs_mask = masks + else: + hs_mask = streaming_mask + + return hidden_states, hs_mask, masks + + def calculate_hs_mask(self, hidden_states, device, mask): + max_audio_length = hidden_states.shape[1] + batch_size = hidden_states.shape[0] + enc_streaming_mask = self._streaming_mask( + max_audio_length, batch_size, self.config.chunk_size, self.config.left_chunk + ) + enc_streaming_mask = enc_streaming_mask.to(device) + if mask is None: + return enc_streaming_mask + + feature_lens = mask.sum(1) + padding_length = feature_lens + pad_mask = torch.arange(0, max_audio_length, device=device).expand( + padding_length.size(0), -1 + ) < padding_length.unsqueeze(1) + pad_mask = pad_mask.unsqueeze(1) + pad_mask = pad_mask & enc_streaming_mask + return pad_mask + + def forward(self, hidden_states: torch.Tensor, mask: torch.Tensor | None, **kwargs): + hidden_states = self.encoder_embedding(hidden_states) + hidden_states, hs_mask, mask = self.forward_embeddings(hidden_states, mask) + + unfolded = False + bs, seq_len, _ = hidden_states.shape + max_seq_len = 500 # maximum position for absolute positional encoding + if seq_len > max_seq_len: + # audio sequence is longer than max_seq_len, unfold it into chunks of max_seq_len + unfolded = True + # the unfold op will drop residual frames, pad it to the multiple of max_seq_len + if seq_len % max_seq_len > 0: + chunk_pad_size = max_seq_len - (seq_len % max_seq_len) + else: + chunk_pad_size = 0 + if chunk_pad_size > 0: + hidden_states_pad = F.pad(hidden_states, (0, 0, 0, chunk_pad_size), "constant", 0) + hidden_states = hidden_states_pad.to(hidden_states.device) + + hidden_states = unfold_tensor(hidden_states, max_seq_len) + masks_unfold = None + if mask is not None: + # revise hs_mask here because the previous calculated hs_mask did not consider extra pad + subsampled_pad_mask = mask.squeeze(1) # [bz, subsampled_unmask_seq_len] + extra_padded_subsamlped_pad_mask = F.pad( + subsampled_pad_mask, (0, chunk_pad_size), "constant", False + ) # extra padding to the pad mask + extra_padded_subsamlped_pad_mask = extra_padded_subsamlped_pad_mask.unsqueeze(-1).float() + masks_unfold = unfold_tensor( + extra_padded_subsamlped_pad_mask, max_seq_len + ) # unfold the pad mask like we did to the input tensor + masks_unfold = masks_unfold.squeeze(-1).bool() # unfold op does not support bool tensor + hs_mask = self.calculate_hs_mask( + hidden_states, hidden_states.device, masks_unfold + ) # calculate hs_mask based on the unfolded pad mask + + relative_attention_bias = self.relative_attention_bias_layer(hidden_states) + attention_mask = hs_mask.unsqueeze(1) + relative_attention_bias + + for layer in self.encoders: + hidden_states = layer(hidden_states, attention_mask) + + if unfolded: + embed_dim = hidden_states.shape[-1] + hidden_states = hidden_states.reshape(bs, -1, embed_dim) + # if we ever padded before unfolding, we need to remove the padding + if chunk_pad_size > 0: + hidden_states = hidden_states[:, :-chunk_pad_size, :] + + return hidden_states + + +class Phi4MultimodalAudioEmbedding(nn.Module): + def __init__(self, config: Phi4MultimodalConfig): + super().__init__() + self.config = config + self.layer_idx = config.audio_config.feature_layer + + self.drop = nn.Dropout(config.embd_pdrop) + self.encoder = Phi4MultimodalAudioModel._from_config(config.audio_config) + self.up_proj_for_speech = nn.Linear( + config.audio_config.hidden_size * config.audio_config.downsample_rate, config.hidden_size + ) + self.down_proj_for_speech = nn.Linear(config.hidden_size, config.hidden_size) + self.up_proj_for_vision_speech = nn.Linear( + config.audio_config.hidden_size * config.audio_config.downsample_rate, config.hidden_size + ) + self.down_proj_for_vision_speech = nn.Linear(config.hidden_size, config.hidden_size) + + def forward( + self, + input_ids: torch.LongTensor, + inputs_embeds: torch.Tensor, + audio_input_features: torch.FloatTensor, + audio_embed_sizes=None, + audio_attention_mask=None, + audio_projection_mode="speech", + ) -> torch.FloatTensor: + with torch.no_grad(): + positions_tuple = torch.nonzero(input_ids == self.config.audio_config.audio_token_id, as_tuple=True) + + up_proj = self.up_proj_for_speech if audio_projection_mode == "speech" else self.up_proj_for_vision_speech + down_proj = ( + self.down_proj_for_speech if audio_projection_mode == "speech" else self.down_proj_for_vision_speech + ) + + target_device = up_proj.bias.device + target_dtype = up_proj.bias.dtype + + audio_input_features = audio_input_features.to(device=target_device, dtype=target_dtype) + + audio_encoder_hidden_states = self.encoder(audio_input_features, audio_attention_mask) + audio_encoder_hidden_states = up_proj(audio_encoder_hidden_states) + audio_encoder_hidden_states = nn.functional.gelu(audio_encoder_hidden_states) + audio_embeds = down_proj(audio_encoder_hidden_states) + + merged_audio_embeds = torch.cat( + [audio_embeds[i, : audio_embed_sizes[i], :] for i in range(len(audio_embed_sizes))], dim=0 + ) + merged_audio_embeds = merged_audio_embeds.to(dtype=inputs_embeds.dtype, device=inputs_embeds.device) + # Temporarily disable autocast to avoid issue on bf16 tensors + # Ref: https://github.com/pytorch/pytorch/issues/132715 + with maybe_autocast(device_type=inputs_embeds.device.type, enabled=False): + audio_embeds = inputs_embeds.index_put( + indices=positions_tuple, values=merged_audio_embeds, accumulate=False + ) + + audio_embeds = self.drop(audio_embeds) + + return audio_embeds + + +@use_kernel_forward_from_hub("RMSNorm") +class Phi4MultimodalRMSNorm(nn.Module): + def __init__(self, hidden_size, eps: float = 1e-6) -> None: + """ + Phi4MultimodalRMSNorm is equivalent to T5LayerNorm + """ + super().__init__() + self.weight = nn.Parameter(torch.ones(hidden_size)) + self.variance_epsilon = eps + + def forward(self, hidden_states: torch.Tensor) -> torch.Tensor: + input_dtype = hidden_states.dtype + hidden_states = hidden_states.to(torch.float32) + variance = hidden_states.pow(2).mean(-1, keepdim=True) + hidden_states = hidden_states * torch.rsqrt(variance + self.variance_epsilon) + return self.weight * hidden_states.to(input_dtype) + + def extra_repr(self): + return f"{tuple(self.weight.shape)}, eps={self.variance_epsilon}" + + +class Phi4MultimodalMLP(nn.Module): + def __init__(self, config): + super().__init__() + + self.config = config + self.gate_up_proj = nn.Linear(config.hidden_size, 2 * config.intermediate_size, bias=False) + self.down_proj = nn.Linear(config.intermediate_size, config.hidden_size, bias=False) + self.activation_fn = ACT2FN[config.hidden_act] + + def forward(self, hidden_states: torch.FloatTensor) -> torch.FloatTensor: + up_states = self.gate_up_proj(hidden_states) + + gate, up_states = up_states.chunk(2, dim=-1) + up_states = up_states * self.activation_fn(gate) + + return self.down_proj(up_states) + + +def rotate_half(x): + """Rotates half the hidden dims of the input.""" + x1 = x[..., : x.shape[-1] // 2] + x2 = x[..., x.shape[-1] // 2 :] + return torch.cat((-x2, x1), dim=-1) + + +def repeat_kv(hidden_states: torch.Tensor, n_rep: int) -> torch.Tensor: + """ + This is the equivalent of torch.repeat_interleave(x, dim=1, repeats=n_rep). The hidden states go from (batch, + num_key_value_heads, seqlen, head_dim) to (batch, num_attention_heads, seqlen, head_dim) + """ + batch, num_key_value_heads, slen, head_dim = hidden_states.shape + if n_rep == 1: + return hidden_states + hidden_states = hidden_states[:, :, None, :, :].expand(batch, num_key_value_heads, n_rep, slen, head_dim) + return hidden_states.reshape(batch, num_key_value_heads * n_rep, slen, head_dim) + + +def eager_attention_forward( + module: nn.Module, + query: torch.Tensor, + key: torch.Tensor, + value: torch.Tensor, + attention_mask: torch.Tensor | None, + scaling: float, + dropout: float = 0.0, + **kwargs: Unpack[TransformersKwargs], +): + key_states = repeat_kv(key, module.num_key_value_groups) + value_states = repeat_kv(value, module.num_key_value_groups) + + attn_weights = torch.matmul(query, key_states.transpose(2, 3)) * scaling + if attention_mask is not None: + attn_weights = attn_weights + attention_mask + + attn_weights = nn.functional.softmax(attn_weights, dim=-1, dtype=torch.float32).to(query.dtype) + attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training) + attn_output = torch.matmul(attn_weights, value_states) + attn_output = attn_output.transpose(1, 2).contiguous() + + return attn_output, attn_weights + + +def apply_rotary_pos_emb(q, k, cos, sin, unsqueeze_dim=1): + """Applies Rotary Position Embedding to the query and key tensors. + + Args: + q (`torch.Tensor`): The query tensor. + k (`torch.Tensor`): The key tensor. + cos (`torch.Tensor`): The cosine part of the rotary embedding. + sin (`torch.Tensor`): The sine part of the rotary embedding. + unsqueeze_dim (`int`, *optional*, defaults to 1): + The 'unsqueeze_dim' argument specifies the dimension along which to unsqueeze cos[position_ids] and + sin[position_ids] so that they can be properly broadcasted to the dimensions of q and k. For example, note + that cos[position_ids] and sin[position_ids] have the shape [batch_size, seq_len, head_dim]. Then, if q and + k have the shape [batch_size, heads, seq_len, head_dim], then setting unsqueeze_dim=1 makes + cos[position_ids] and sin[position_ids] broadcastable to the shapes of q and k. Similarly, if q and k have + the shape [batch_size, seq_len, heads, head_dim], then set unsqueeze_dim=2. + Returns: + `tuple(torch.Tensor)` comprising of the query and key tensors rotated using the Rotary Position Embedding. + """ + cos = cos.unsqueeze(unsqueeze_dim) + sin = sin.unsqueeze(unsqueeze_dim) + + rotary_dim = cos.shape[-1] + q_rot, q_pass = q[..., :rotary_dim], q[..., rotary_dim:] + k_rot, k_pass = k[..., :rotary_dim], k[..., rotary_dim:] + + q_embed = torch.cat([(q_rot * cos) + (rotate_half(q_rot) * sin), q_pass], dim=-1) + k_embed = torch.cat([(k_rot * cos) + (rotate_half(k_rot) * sin), k_pass], dim=-1) + return q_embed, k_embed + + +class Phi4MultimodalAttention(nn.Module): + """Multi-headed attention from 'Attention Is All You Need' paper""" + + def __init__(self, config: Phi4MultimodalConfig, layer_idx: int | None = None): + super().__init__() + self.config = config + self.layer_idx = layer_idx + self.head_dim = getattr(config, "head_dim", config.hidden_size // config.num_attention_heads) + self.num_key_value_groups = config.num_attention_heads // config.num_key_value_heads + self.num_key_value_heads = config.num_key_value_heads + self.scaling = self.head_dim**-0.5 + self.attention_dropout = config.attention_dropout + self.is_causal = True + + op_size = config.num_attention_heads * self.head_dim + 2 * (config.num_key_value_heads * self.head_dim) + self.o_proj = nn.Linear(config.num_attention_heads * self.head_dim, config.hidden_size, bias=False) + self.qkv_proj = nn.Linear(config.hidden_size, op_size, bias=False) + + def forward( + self, + hidden_states: torch.Tensor, + position_embeddings: tuple[torch.Tensor, torch.Tensor], + attention_mask: torch.Tensor | None, + past_key_values: Cache | None = None, + cache_position: torch.LongTensor | None = None, + **kwargs: Unpack[FlashAttentionKwargs], + ) -> tuple[torch.Tensor, torch.Tensor | None, tuple[torch.Tensor] | None]: + input_shape = hidden_states.shape[:-1] + hidden_shape = (*input_shape, -1, self.head_dim) + + qkv = self.qkv_proj(hidden_states) + query_pos = self.config.num_attention_heads * self.head_dim + query_states = qkv[..., :query_pos] + key_states = qkv[..., query_pos : query_pos + self.num_key_value_heads * self.head_dim] + value_states = qkv[..., query_pos + self.num_key_value_heads * self.head_dim :] + + query_states = query_states.view(hidden_shape).transpose(1, 2) + key_states = key_states.view(hidden_shape).transpose(1, 2) + value_states = value_states.view(hidden_shape).transpose(1, 2) + + cos, sin = position_embeddings + query_states, key_states = apply_rotary_pos_emb(query_states, key_states, cos, sin) + + if past_key_values is not None: + # sin and cos are specific to RoPE models; cache_position needed for the static cache + cache_kwargs = {"sin": sin, "cos": cos, "cache_position": cache_position} + key_states, value_states = past_key_values.update(key_states, value_states, self.layer_idx, cache_kwargs) + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, eager_attention_forward + ) + + attn_output, attn_weights = attention_interface( + self, + query_states, + key_states, + value_states, + attention_mask, + dropout=0.0 if not self.training else self.attention_dropout, + scaling=self.scaling, + sliding_window=getattr(self.config, "sliding_window", None), + **kwargs, + ) + + attn_output = attn_output.reshape(*input_shape, -1).contiguous() + attn_output = self.o_proj(attn_output) + return attn_output, attn_weights + + +class Phi4MultimodalDecoderLayer(GradientCheckpointingLayer): + def __init__(self, config: Phi4MultimodalConfig, layer_idx: int): + super().__init__() + self.hidden_size = config.hidden_size + self.self_attn = Phi4MultimodalAttention(config=config, layer_idx=layer_idx) + self.mlp = Phi4MultimodalMLP(config) + self.input_layernorm = Phi4MultimodalRMSNorm(config.hidden_size, eps=config.rms_norm_eps) + self.post_attention_layernorm = Phi4MultimodalRMSNorm(config.hidden_size, eps=config.rms_norm_eps) + self.config = config + self.resid_attn_dropout = nn.Dropout(config.resid_pdrop) + self.resid_mlp_dropout = nn.Dropout(config.resid_pdrop) + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.Tensor | None = None, + position_ids: torch.LongTensor | None = None, + past_key_values: Cache | None = None, + use_cache: bool | None = False, + cache_position: torch.LongTensor | None = None, + position_embeddings: tuple[torch.Tensor, torch.Tensor] | None = None, + **kwargs: Unpack[FlashAttentionKwargs], + ) -> tuple[torch.FloatTensor, tuple[torch.FloatTensor, torch.FloatTensor] | None]: + residual = hidden_states + hidden_states = self.input_layernorm(hidden_states) + + hidden_states, self_attn_weights = self.self_attn( + hidden_states=hidden_states, + attention_mask=attention_mask, + position_ids=position_ids, + past_key_values=past_key_values, + use_cache=use_cache, + cache_position=cache_position, + position_embeddings=position_embeddings, + **kwargs, + ) + hidden_states = residual + self.resid_attn_dropout(hidden_states) # main diff with Llama + + residual = hidden_states + hidden_states = self.post_attention_layernorm(hidden_states) + hidden_states = self.mlp(hidden_states) + hidden_states = residual + self.resid_mlp_dropout(hidden_states) # main diff with Llama + return hidden_states + + +class Phi4MultimodalFeatureEmbedding(nn.Module): + """Image-audio embedding.""" + + def __init__(self, config: Phi4MultimodalConfig) -> None: + super().__init__() + self.config = config + self.image_token_id = config.vision_config.image_token_id + self.audio_token_id = config.audio_config.audio_token_id + self.image_embed = Phi4MultimodalImageEmbedding(config) + self.audio_embed = Phi4MultimodalAudioEmbedding(config) + + def forward( + self, + input_ids: torch.LongTensor, + inputs_embeds: torch.Tensor, + image_pixel_values: torch.FloatTensor | None = None, + audio_input_features: torch.FloatTensor | None = None, + image_sizes=None, + image_attention_mask=None, + audio_embed_sizes=None, + audio_attention_mask=None, + ) -> torch.FloatTensor: + with torch.no_grad(): + image_position_mask = (input_ids == self.config.vision_config.image_token_id).unsqueeze(-1) + non_image_position_mask = ~image_position_mask + + image_embeds = None + audio_embeds = None + if image_pixel_values is not None and (input_ids == self.image_token_id).any(): + image_embeds = self.image_embed( + input_ids, + inputs_embeds, + image_pixel_values=image_pixel_values, + image_sizes=image_sizes, + image_attention_mask=image_attention_mask, + ) + if audio_input_features is not None and (input_ids == self.audio_token_id).any(): + audio_projection_mode = "vision" if image_pixel_values is not None else "speech" + audio_embeds = self.audio_embed( + input_ids, + inputs_embeds, + audio_input_features=audio_input_features, + audio_embed_sizes=audio_embed_sizes, + audio_attention_mask=audio_attention_mask, + audio_projection_mode=audio_projection_mode, + ) + + # merge image and audio + if image_embeds is not None and audio_embeds is not None: + inputs_embeds = image_embeds * image_position_mask + audio_embeds * non_image_position_mask + elif image_embeds is not None: + inputs_embeds = image_embeds + elif audio_embeds is not None: + inputs_embeds = audio_embeds + + return inputs_embeds + + +@auto_docstring +class Phi4MultimodalPreTrainedModel(PreTrainedModel): + config: Phi4MultimodalConfig + base_model_prefix = "model" + supports_gradient_checkpointing = True + _no_split_modules = ["Phi4MultimodalDecoderLayer"] + _skip_keys_device_placement = ["past_key_values"] + _supports_flash_attn = True + _supports_sdpa = True + _supports_flex_attn = True + + _can_compile_fullgraph = True + _supports_attention_backend = True + _can_record_outputs = { + "hidden_states": Phi4MultimodalDecoderLayer, + "attentions": Phi4MultimodalAttention, + } + _version = "0.0.5" + input_modalities = ("image", "audio", "text") + + @torch.no_grad() + def _init_weights(self, module): + super()._init_weights(module) + if isinstance(module, Phi4MultimodalImageEmbedding): + init.zeros_(module.global_img_feature_extensor) + init.zeros_(module.sub_img_feature_extensor) + + +class Phi4MultimodalRotaryEmbedding(nn.Module): + inv_freq: torch.Tensor # fix linting for `register_buffer` + + def __init__(self, config: Phi4MultimodalConfig, device=None): + super().__init__() + self.max_seq_len_cached = config.max_position_embeddings + self.original_max_seq_len = config.max_position_embeddings + + self.config = config + + self.rope_type = self.config.rope_parameters["rope_type"] + rope_init_fn: Callable = self.compute_default_rope_parameters + if self.rope_type != "default": + rope_init_fn = ROPE_INIT_FUNCTIONS[self.rope_type] + inv_freq, self.attention_scaling = rope_init_fn(self.config, device) + + self.register_buffer("inv_freq", inv_freq, persistent=False) + self.register_buffer("original_inv_freq", inv_freq.clone(), persistent=False) + + @staticmethod + def compute_default_rope_parameters( + config: Phi4MultimodalConfig | None = None, + device: Optional["torch.device"] = None, + seq_len: int | None = None, + ) -> tuple["torch.Tensor", float]: + """ + Computes the inverse frequencies according to the original RoPE implementation + Args: + config ([`~transformers.PreTrainedConfig`]): + The model configuration. + device (`torch.device`): + The device to use for initialization of the inverse frequencies. + seq_len (`int`, *optional*): + The current sequence length. Unused for this type of RoPE. + Returns: + Tuple of (`torch.Tensor`, `float`), containing the inverse frequencies for the RoPE embeddings and the + post-processing scaling factor applied to the computed cos/sin (unused in this type of RoPE). + """ + base = config.rope_parameters["rope_theta"] + partial_rotary_factor = config.rope_parameters.get("partial_rotary_factor", 1.0) + head_dim = getattr(config, "head_dim", None) or config.hidden_size // config.num_attention_heads + dim = int(head_dim * partial_rotary_factor) + + attention_factor = 1.0 # Unused in this type of RoPE + + # Compute the inverse frequencies + inv_freq = 1.0 / ( + base ** (torch.arange(0, dim, 2, dtype=torch.int64).to(device=device, dtype=torch.float) / dim) + ) + return inv_freq, attention_factor + + @torch.no_grad() + @dynamic_rope_update # power user: used with advanced RoPE types (e.g. dynamic rope) + def forward(self, x, position_ids): + inv_freq_expanded = self.inv_freq[None, :, None].float().expand(position_ids.shape[0], -1, 1).to(x.device) + position_ids_expanded = position_ids[:, None, :].float() + + device_type = x.device.type if isinstance(x.device.type, str) and x.device.type != "mps" else "cpu" + with maybe_autocast(device_type=device_type, enabled=False): # Force float32 + freqs = (inv_freq_expanded.float() @ position_ids_expanded.float()).transpose(1, 2) + emb = torch.cat((freqs, freqs), dim=-1) + cos = emb.cos() * self.attention_scaling + sin = emb.sin() * self.attention_scaling + + return cos.to(dtype=x.dtype), sin.to(dtype=x.dtype) + + +@auto_docstring +class Phi4MultimodalModel(Phi4MultimodalPreTrainedModel): + def __init__(self, config: Phi4MultimodalConfig): + super().__init__(config) + self.padding_idx = config.pad_token_id + self.vocab_size = config.vocab_size + + self.embed_tokens = nn.Embedding(config.vocab_size, config.hidden_size, self.padding_idx) + + self.layers = nn.ModuleList( + [Phi4MultimodalDecoderLayer(config, layer_idx) for layer_idx in range(config.num_hidden_layers)] + ) + self.norm = Phi4MultimodalRMSNorm(config.hidden_size, eps=config.rms_norm_eps) + self.rotary_emb = Phi4MultimodalRotaryEmbedding(config=config) + + self.gradient_checkpointing = False + self.embed_dropout = nn.Dropout(config.embd_pdrop) + + self.embed_tokens_extend = Phi4MultimodalFeatureEmbedding(config) + + # Initialize weights and apply final processing + self.post_init() + + @merge_with_config_defaults + @capture_outputs + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.Tensor | None = None, + position_ids: torch.LongTensor | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.FloatTensor | None = None, + image_pixel_values: torch.FloatTensor | None = None, + image_sizes: torch.LongTensor | None = None, + image_attention_mask=None, + audio_input_features: torch.FloatTensor | None = None, + audio_embed_sizes=None, + audio_attention_mask=None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + cache_position: torch.LongTensor | None = None, + **kwargs, + ) -> tuple | BaseModelOutputWithPast: + r""" + image_pixel_values (`torch.FloatTensor`, *optional*): + If the input contains images, these correspond to the pixel values after transformations (as returned by + the Processor) + image_sizes (`torch.LongTensor`, *optional*): + If the input contains images, these correspond to size of each image. + image_attention_mask (`torch.LongTensor`, *optional*): + Attention mask for the images. + audio_input_features (`torch.FloatTensor`, *optional*): + If the input contains audio samples, these correspond to the values after transformation (as returned by + the Processor). + audio_embed_sizes (`torch.Tensor`, *optional*): + Size of the audio inputs. + audio_attention_mask (`torch.Tensor, *optional*): + Attention mask for the audio inputs. + """ + if (input_ids is None) ^ (inputs_embeds is not None): + raise ValueError("You must specify exactly one of input_ids or inputs_embeds") + if use_cache and past_key_values is None: + past_key_values = DynamicCache(config=self.config) + + if inputs_embeds is None: + inputs_embeds = self.embed_tokens(input_ids) + inputs_embeds = self.embed_tokens_extend( + input_ids, + inputs_embeds, + image_pixel_values=image_pixel_values, + audio_input_features=audio_input_features, + image_sizes=image_sizes, + image_attention_mask=image_attention_mask, + audio_embed_sizes=audio_embed_sizes, + audio_attention_mask=audio_attention_mask, + ) + + if cache_position is None: + past_seen_tokens = past_key_values.get_seq_length() if past_key_values is not None else 0 + cache_position = torch.arange( + past_seen_tokens, past_seen_tokens + inputs_embeds.shape[1], device=inputs_embeds.device + ) + if position_ids is None: + position_ids = cache_position.unsqueeze(0) + + mask_function = create_causal_mask if self.config.sliding_window is None else create_sliding_window_causal_mask + causal_mask = mask_function( + config=self.config, + inputs_embeds=inputs_embeds, + attention_mask=attention_mask, + cache_position=cache_position, + past_key_values=past_key_values, + position_ids=position_ids, + ) + + hidden_states = inputs_embeds + position_embeddings = self.rotary_emb(hidden_states, position_ids=position_ids) + + for decoder_layer in self.layers: + hidden_states = decoder_layer( + hidden_states, + attention_mask=causal_mask, + position_ids=position_ids, + past_key_values=past_key_values, + use_cache=use_cache, + cache_position=cache_position, + position_embeddings=position_embeddings, + **kwargs, + ) + + hidden_states = self.norm(hidden_states) + return BaseModelOutputWithPast( + last_hidden_state=hidden_states, + past_key_values=past_key_values if use_cache else None, + ) + + +@auto_docstring +class Phi4MultimodalForCausalLM(Phi4MultimodalPreTrainedModel, GenerationMixin): + _tied_weights_keys = {"lm_head.weight": "model.embed_tokens.weight"} + _tp_plan = {"lm_head": "colwise_gather_output"} + _pp_plan = {"lm_head": (["hidden_states"], ["logits"])} + + def __init__(self, config): + super().__init__(config) + self.model = Phi4MultimodalModel(config) + self.vocab_size = config.vocab_size + self.lm_head = nn.Linear(config.hidden_size, config.vocab_size, bias=False) + + # Initialize weights and apply final processing + self.post_init() + + @can_return_tuple + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.Tensor | None = None, + position_ids: torch.LongTensor | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.FloatTensor | None = None, + image_pixel_values: torch.FloatTensor | None = None, + image_sizes: torch.LongTensor | None = None, + image_attention_mask=None, + audio_input_features: torch.FloatTensor | None = None, + audio_embed_sizes=None, + audio_attention_mask=None, + labels: torch.LongTensor | None = None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + cache_position: torch.LongTensor | None = None, + logits_to_keep: int | torch.Tensor = 0, + **kwargs, + ) -> CausalLMOutputWithPast: + r""" + image_pixel_values (`torch.FloatTensor`, *optional*): + If the input contains images, these correspond to the pixel values after transformations (as returned by + the Processor) + image_sizes (`torch.LongTensor`, *optional*): + If the input contains images, these correspond to size of each image. + image_attention_mask (`torch.LongTensor`, *optional*): + Attention mask for the images. + audio_input_features (`torch.FloatTensor`, *optional*): + If the input contains audio samples, these correspond to the values after transformation (as returned by + the Processor). + audio_embed_sizes (`torch.Tensor`, *optional*): + Size of the audio inputs. + audio_attention_mask (`torch.Tensor, *optional*): + Attention mask for the audio inputs. + labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Labels for computing the masked language modeling loss. Indices should either be in `[0, ..., + config.vocab_size]` or -100 (see `input_ids` docstring). Tokens with indices set to `-100` are ignored + (masked), the loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]`. + + Example: + ```python + >>> from transformers import AutoTokenizer, Phi4MultimodalForCausalLM + >>> model = Phi4MultimodalForCausalLM.from_pretrained("TBA") + >>> tokenizer = AutoTokenizer.from_pretrained("TBA") + >>> prompt = "This is an example script ." + >>> inputs = tokenizer(prompt, return_tensors="pt") + >>> # Generate + >>> generate_ids = model.generate(inputs.input_ids, max_length=30) + >>> tokenizer.batch_decode(generate_ids, skip_special_tokens=True, clean_up_tokenization_spaces=False)[0] + 'This is an example script .\n Certainly! Below is a sample script that demonstrates a simple task, such as calculating the sum' + ```""" + + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + + # decoder outputs consists of (dec_features, layer_state, dec_hidden, dec_attn) + outputs: BaseModelOutputWithPast = self.model( + input_ids=input_ids, + attention_mask=attention_mask, + position_ids=position_ids, + past_key_values=past_key_values, + inputs_embeds=inputs_embeds, + image_pixel_values=image_pixel_values, + image_sizes=image_sizes, + image_attention_mask=image_attention_mask, + audio_input_features=audio_input_features, + audio_embed_sizes=audio_embed_sizes, + audio_attention_mask=audio_attention_mask, + use_cache=use_cache, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + cache_position=cache_position, + **kwargs, + ) + + hidden_states = outputs.last_hidden_state + # Only compute necessary logits, and do not upcast them to float if we are not computing the loss + slice_indices = slice(-logits_to_keep, None) if isinstance(logits_to_keep, int) else logits_to_keep + logits = self.lm_head(hidden_states[:, slice_indices, :]) + + loss = None + if labels is not None: + loss = self.loss_function(logits, labels, self.vocab_size) + + return CausalLMOutputWithPast( + loss=loss, + logits=logits, + past_key_values=outputs.past_key_values, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + ) + + def prepare_inputs_for_generation( + self, + input_ids, + past_key_values=None, + attention_mask=None, + inputs_embeds=None, + image_pixel_values=None, + image_sizes=None, + image_attention_mask=None, + audio_input_features=None, + audio_embed_sizes=None, + audio_attention_mask=None, + cache_position=None, + position_ids=None, + use_cache=True, + logits_to_keep=0, + **kwargs, + ): + # Overwritten -- this model may need to switch between short and long rope, invalidating the cache in the + # process + + # When the first time input length reached long and short factor switching point, enforce re-compute cache + # It will cause downside of slower at this single token position, however, better than current failure. + if ( + past_key_values + and self.config.rope_parameters + and input_ids.shape[1] >= self.config.original_max_position_embeddings + 1 + ): + past_length = cache_position[0] + if past_length <= self.config.original_max_position_embeddings: + past_key_values = None + + model_inputs = super().prepare_inputs_for_generation( + input_ids=input_ids, + past_key_values=past_key_values, + attention_mask=attention_mask, + inputs_embeds=inputs_embeds, + image_pixel_values=image_pixel_values, + image_sizes=image_sizes, + image_attention_mask=image_attention_mask, + audio_input_features=audio_input_features, + audio_embed_sizes=audio_embed_sizes, + audio_attention_mask=audio_attention_mask, + cache_position=cache_position, + position_ids=position_ids, + use_cache=use_cache, + logits_to_keep=logits_to_keep, + **kwargs, + ) + return model_inputs + + +__all__ = [ + "Phi4MultimodalAudioPreTrainedModel", + "Phi4MultimodalAudioModel", + "Phi4MultimodalVisionPreTrainedModel", + "Phi4MultimodalVisionModel", + "Phi4MultimodalPreTrainedModel", + "Phi4MultimodalModel", + "Phi4MultimodalForCausalLM", +] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/phi4_multimodal/modular_phi4_multimodal.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/phi4_multimodal/modular_phi4_multimodal.py new file mode 100644 index 0000000000000000000000000000000000000000..4e96909c8513cbd77ecad824d9532f0ab04ba9ae --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/phi4_multimodal/modular_phi4_multimodal.py @@ -0,0 +1,1751 @@ +# Copyright 2025 Microsoft and the HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import math +from collections.abc import Callable + +import numpy as np +import torch +import torch.nn.functional as F +from torch import nn + +from ... import initialization as init +from ...activations import ACT2FN +from ...cache_utils import Cache, DynamicCache +from ...configuration_utils import PreTrainedConfig +from ...masking_utils import create_bidirectional_mask, create_causal_mask, create_sliding_window_causal_mask +from ...modeling_outputs import ( + BaseModelOutput, + BaseModelOutputWithPast, + BaseModelOutputWithPooling, + CausalLMOutputWithPast, +) +from ...modeling_rope_utils import RopeParameters +from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel +from ...processing_utils import Unpack +from ...utils import auto_docstring, logging +from ...utils.generic import ( + TransformersKwargs, + maybe_autocast, + merge_with_config_defaults, +) +from ...utils.output_capturing import capture_outputs +from ..phi3.configuration_phi3 import Phi3Config +from ..phi3.modeling_phi3 import ( + Phi3DecoderLayer, + Phi3ForCausalLM, + Phi3Model, + Phi3PreTrainedModel, + Phi3RMSNorm, +) +from ..siglip.configuration_siglip import SiglipVisionConfig +from ..siglip.modeling_siglip import ( + SiglipEncoder, + SiglipEncoderLayer, + SiglipMLP, + SiglipMultiheadAttentionPoolingHead, + SiglipPreTrainedModel, + SiglipVisionEmbeddings, +) + + +logger = logging.get_logger(__name__) + + +class Phi4MultimodalVisionConfig(SiglipVisionConfig): + r""" + This is the configuration class to store the configuration of a [`Phi4MultimodalVisionModel`]. It is used to instantiate a + Phi4Multimodal vision encoder according to the specified arguments, defining the model architecture. Instantiating a + configuration with the defaults will yield a similar configuration to that of the vision encoder of + [microsoft/Phi-4-multimodal-instruct](https://huggingface.co/microsoft/Phi-4-multimodal-instruct) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + hidden_size (`int`, *optional*, defaults to 1152): + Dimensionality of the encoder layers and the pooler layer. + intermediate_size (`int`, *optional*, defaults to 4304): + Dimensionality of the "intermediate" (i.e., feed-forward) layer in the Transformer encoder. + num_hidden_layers (`int`, *optional*, defaults to 27): + Number of hidden layers in the Transformer encoder. + num_attention_heads (`int`, *optional*, defaults to 16): + Number of attention heads for each attention layer in the Transformer encoder. + num_channels (`int`, *optional*, defaults to 3): + Number of channels in the input images. + image_size (`int`, *optional*, defaults to 448): + The size (resolution) of each image. + patch_size (`int`, *optional*, defaults to 14): + The size (resolution) of each patch. + hidden_act (`str` or `function`, *optional*, defaults to `"gelu_pytorch_tanh"`): + The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`, + `"relu"`, `"selu"` and `"gelu_new"` `"quick_gelu"` are supported. + layer_norm_eps (`float`, *optional*, defaults to 1e-06): + The epsilon used by the layer normalization layers. + attention_dropout (`float`, *optional*, defaults to 0.0): + The dropout ratio for the attention probabilities. + crop_size (`int`, *optional*, defaults to 448): + Crop size for the input images. + image_token_id (`int`, *optional*, defaults to 200010): + The image token id. + feature_layer (`int`, *optional*, defaults to -2): + The index of the layer of the encoder from which to extract image features. + + Example: + + ```python + >>> from transformers import Phi4MultimodalVisionConfig + + >>> # Initializing a Phi4MultimodalVisionConfig with microsoft/Phi-4-multimodal-instruct style configuration + >>> configuration = Phi4MultimodalVisionConfig() + ```""" + + model_type = "phi4_multimodal_vision" + + def __init__( + self, + hidden_size=1152, + intermediate_size=4304, + num_hidden_layers=27, + num_attention_heads=16, + num_channels=3, + image_size=448, + patch_size=14, + hidden_act="gelu_pytorch_tanh", + layer_norm_eps=1e-6, + attention_dropout=0.0, + crop_size: int = 448, + image_token_id: int = 200010, + feature_layer: int = -2, + **kwargs, + ): + super().__init__( + hidden_size=hidden_size, + intermediate_size=intermediate_size, + num_hidden_layers=num_hidden_layers, + num_attention_heads=num_attention_heads, + num_channels=num_channels, + image_size=image_size, + patch_size=patch_size, + hidden_act=hidden_act, + layer_norm_eps=layer_norm_eps, + attention_dropout=attention_dropout, + **kwargs, + ) + self.crop_size = crop_size + self.image_token_id = image_token_id + self.feature_layer = feature_layer + + +class Phi4MultimodalAudioConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`Phi4MultimodalAudioModel`]. It is used to instantiate a + Phi4Multimodal audio encoder according to the specified arguments, defining the model architecture. Instantiating a + configuration with the defaults will yield a similar configuration to that of the audio encoder of + [microsoft/Phi-4-multimodal-instruct](https://huggingface.co/microsoft/Phi-4-multimodal-instruct) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + hidden_size (`int`, *optional*, defaults to 1024): + Dimensionality of the encoder layers. + intermediate_size (`int`, *optional*, defaults to 1536): + Dimensionality of the "intermediate" (i.e., feed-forward) layer in the Transformer encoder. + num_blocks (`int`, *optional*, defaults to 24): + Number of hidden layers in the Transformer encoder. + num_attention_heads (`int`, *optional*, defaults to 16): + Number of attention heads for each attention layer in the Transformer encoder. + activation (`str`, *optional*, defaults to `"swish"`): + The non-linear activation function in the MLPs. + chunk_size (`int`, *optional*, defaults to -1): + The chunk size to create the masks. + left_chunk (`int`, *optional*, defaults to 18): + The left chunk to create the masks. + dropout_rate (`float`, *optional*, defaults to 0.0): + The dropout ratio. + ext_pw_out_channel (`int`, *optional*, defaults to 1024): + Number of out channels in the point-wise conv modules. + depthwise_separable_out_channel (`int`, *optional*, defaults to 1024): + Number of out channels in the depth-wise separable conv modules. + depthwise_multiplier (`int`, *optional*, defaults to 1): + Input size multiplier for the depth-wise separable conv modules. + kernel_size (`int`, *optional*, defaults to 3): + Kernel size for the depth-wise separable conv modules. + conv_activation (`str`, *optional*, defaults to `"swish"`): + The non-linear activation function in the conv modules. + input_size (`int`, *optional*, defaults to 80): + Input size for the audio model. + conv_glu_type (`str`, *optional*, defaults to `"swish"`): + The non-linear activation function in the point-wise conv modules. + time_reduction (`int`, *optional*, defaults to 8): + Time reduction (subsampling factor). + bias_max_distance (`int`, *optional*, defaults to 1000): + Max distance for the relative attention bias module. + bias_symmetric (`bool`, *optional*, defaults to `False`): + Whether the relative attention bias should be symmetric or not. + nemo_activation (`str`, *optional*, defaults to `"relu"`): + The non-linear activation function in the nemo conv modules. + nemo_conv_channels (`int`, *optional*, defaults to 1024): + Number of channels in the nemo conv modules. + downsample_rate (`int`, *optional*, defaults to 1): + Downsample rate for the audio feature extractor. + initializer_range (`float`, *optional*, defaults to 0.02): + The standard deviation of the truncated_normal_initializer for initializing all weight matrices. + audio_token_id (`int`, *optional*, defaults to 200011): + The audio token id. + feature_layer (`int`, *optional*, defaults to -2): + The index of the layer of the encoder from which to extract audio features. + + Example: + + ```python + >>> from transformers import Phi4MultimodalAudioConfig + + >>> # Initializing a Phi4MultimodalAudioConfig with microsoft/Phi-4-multimodal-instruct style configuration + >>> configuration = Phi4MultimodalAudioConfig() + ```""" + + model_type = "phi4_multimodal_audio" + + def __init__( + self, + hidden_size: int = 1024, + intermediate_size: int = 1536, + num_blocks: int = 24, + num_attention_heads: int = 16, + activation: str = "swish", + chunk_size: int = -1, + left_chunk: int = 18, + dropout_rate: float = 0.0, + ext_pw_out_channel: int = 1024, + depthwise_separable_out_channel: int = 1024, + depthwise_multiplier: int = 1, + kernel_size: int = 3, + conv_activation: str = "swish", + input_size: int = 80, + conv_glu_type: str = "swish", + time_reduction: int = 8, + bias_max_distance: int = 1000, + bias_symmetric: bool = False, + nemo_activation: str = "relu", + nemo_conv_channels: int = 1024, + downsample_rate: int = 1, + initializer_range: float = 0.02, + audio_token_id: int = 200011, + feature_layer: int = -2, + **kwargs, + ): + super().__init__(**kwargs) + self.hidden_size = hidden_size + self.num_attention_heads = num_attention_heads + self.intermediate_size = intermediate_size + self.activation = activation + self.chunk_size = chunk_size + self.left_chunk = left_chunk + self.num_blocks = num_blocks + self.dropout_rate = dropout_rate + self.ext_pw_out_channel = ext_pw_out_channel + self.depthwise_separable_out_channel = depthwise_separable_out_channel + self.depthwise_multiplier = depthwise_multiplier + self.kernel_size = kernel_size + self.conv_activation = conv_activation + self.input_size = input_size + self.conv_glu_type = conv_glu_type + self.time_reduction = time_reduction + self.bias_max_distance = bias_max_distance + self.bias_symmetric = bias_symmetric + self.nemo_activation = nemo_activation + self.nemo_conv_channels = nemo_conv_channels + self.downsample_rate = downsample_rate + self.audio_token_id = audio_token_id + self.initializer_range = initializer_range + self.feature_layer = feature_layer + + if time_reduction % 2 != 0: + raise ValueError("`time_reduction` should be a multiple of 2!") + length = input_size + for _ in range(int(math.log2(time_reduction))): + length = math.floor((length - 1) / 2 + 1) + self.nemo_final_size = length + + +class Phi4MultimodalConfig(Phi3Config): + r""" + This is the configuration class to store the configuration of a [`Phi4MultimodalModel`]. It is used to instantiate a + Phi4Multimodal model according to the specified arguments, defining the model architecture. Instantiating a configuration + with the defaults will yield a similar configuration to that of the + [microsoft/Phi-4-multimodal-instruct](https://huggingface.co/microsoft/Phi-4-multimodal-instruct) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + vocab_size (`int`, *optional*, defaults to 200064): + Vocabulary size of the Phi-3 model. Defines the number of different tokens that can be represented by the + `inputs_ids` passed when calling [`Phi3Model`]. + hidden_size (`int`, *optional*, defaults to 3072): + Dimension of the hidden representations. + intermediate_size (`int`, *optional*, defaults to 8192): + Dimension of the MLP representations. + num_hidden_layers (`int`, *optional*, defaults to 32): + Number of hidden layers in the Transformer decoder. + num_attention_heads (`int`, *optional*, defaults to 32): + Number of attention heads for each attention layer in the Transformer decoder. + num_key_value_heads (`int`, *optional*, defaults to 8): + This is the number of key_value heads that should be used to implement Grouped Query Attention. If + `num_key_value_heads=num_attention_heads`, the model will use Multi Head Attention (MHA), if + `num_key_value_heads=1` the model will use Multi Query Attention (MQA) otherwise GQA is used. When + converting a multi-head checkpoint to a GQA checkpoint, each group key and value head should be constructed + by meanpooling all the original heads within that group. For more details, check out [this + paper](https://huggingface.co/papers/2305.13245). If it is not specified, will default to + `num_attention_heads`. + resid_pdrop (`float`, *optional*, defaults to 0.0): + Dropout probability for mlp outputs. + embd_pdrop (`int`, *optional*, defaults to 0.0): + The dropout ratio for the embeddings. + attention_dropout (`float`, *optional*, defaults to 0.0): + The dropout ratio after computing the attention scores. + hidden_act (`str` or `function`, *optional*, defaults to `"silu"`): + The non-linear activation function (function or string) in the decoder. + max_position_embeddings (`int`, *optional*, defaults to 131072): + The maximum sequence length that this model might ever be used with. + initializer_range (`float`, *optional*, defaults to 0.02): + The standard deviation of the truncated_normal_initializer for initializing all weight matrices. + rms_norm_eps (`float`, *optional*, defaults to 1e-05): + The epsilon value used for the RMSNorm. + use_cache (`bool`, *optional*, defaults to `True`): + Whether or not the model should return the last key/values attentions (not used by all models). Only + relevant if `config.is_decoder=True`. Whether to tie weight embeddings or not. + tie_word_embeddings (`bool`, *optional*, defaults to `False`): + Whether to tie weight embeddings + rope_parameters (`RopeParameters`, *optional*): + Dictionary containing the configuration parameters for the RoPE embeddings. The dictionary should contain + a value for `rope_theta` and optionally parameters used for scaling in case you want to use RoPE + with longer `max_position_embeddings`. + bos_token_id (`int`, *optional*, defaults to 199999): + The id of the "beginning-of-sequence" token. + eos_token_id (`int` or `list[int]`, *optional*, defaults to `[199999, 200020]`): + The id of the "end-of-sequence" token. + pad_token_id (`int`, *optional*, defaults to 199999): + The id of the padding token. + original_max_position_embeddings (`int`, *optional*, defaults to 4096): + The maximum sequence length that this model was trained with. This is used to determine the size of the + original RoPE embeddings when using long scaling. + sliding_window (`int`, *optional*): + Sliding window attention window size. If `None`, no sliding window is applied. + vision_config (`Phi4MultimodalVisionConfig` or `dict`, *optional*): + The vision config for the underlying image embedding model. If not provided, will default to the configuration + used to instantiate a model similar in architecture as + [microsoft/Phi-4-multimodal-instruct](https://huggingface.co/microsoft/Phi-4-multimodal-instruct). + audio_config (`Phi4MultimodalAudioConfig` or `dict`, *optional*): + The audio config for the underlying audio embedding model. If not provided, will default to the configuration + used to instantiate a model similar in architecture as + [microsoft/Phi-4-multimodal-instruct](https://huggingface.co/microsoft/Phi-4-multimodal-instruct). + + Example: + + ```python + >>> from transformers import Phi4MultimodalModel, Phi4MultimodalConfig + + >>> # Initializing a Phi4Multimodal style configuration + >>> configuration = Phi4MultimodalConfig.from_pretrained("microsoft/Phi-4-multimodal-instruct") + + >>> # Initializing a model from the configuration + >>> model = Phi4MultimodalModel(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + sub_configs = {"audio_config": Phi4MultimodalAudioConfig, "vision_config": Phi4MultimodalVisionConfig} + + def __init__( + self, + vocab_size: int | None = 200064, + hidden_size: int | None = 3072, + intermediate_size: int | None = 8192, + num_hidden_layers: int | None = 32, + num_attention_heads: int | None = 32, + num_key_value_heads: int | None = 8, + resid_pdrop: float | None = 0.0, + embd_pdrop: float | None = 0.0, + attention_dropout: float | None = 0.0, + hidden_act: str | None = "silu", + max_position_embeddings: int | None = 131072, + initializer_range: float | None = 0.02, + rms_norm_eps: int | None = 1e-5, + use_cache: bool | None = True, + tie_word_embeddings: bool | None = False, + rope_parameters: RopeParameters | dict[str, RopeParameters] | None = None, + bos_token_id: int | None = 199999, + eos_token_id: list[int] | None = [199999, 200020], + pad_token_id: int | None = 199999, + original_max_position_embeddings: int | None = 4096, + sliding_window: int | None = None, + vision_config: dict | None = None, + audio_config: dict | None = None, + **kwargs, + ): + if isinstance(vision_config, dict): + vision_config = Phi4MultimodalVisionConfig(**vision_config) + elif vision_config is None: + vision_config = Phi4MultimodalVisionConfig() + self.vision_config = vision_config + + if isinstance(audio_config, dict): + audio_config = Phi4MultimodalAudioConfig(**audio_config) + elif audio_config is None: + audio_config = Phi4MultimodalAudioConfig() + self.audio_config = audio_config + + super().__init__( + vocab_size=vocab_size, + hidden_size=hidden_size, + intermediate_size=intermediate_size, + num_hidden_layers=num_hidden_layers, + num_attention_heads=num_attention_heads, + num_key_value_heads=num_key_value_heads, + resid_pdrop=resid_pdrop, + embd_pdrop=embd_pdrop, + attention_dropout=attention_dropout, + hidden_act=hidden_act, + max_position_embeddings=max_position_embeddings, + initializer_range=initializer_range, + rms_norm_eps=rms_norm_eps, + use_cache=use_cache, + tie_word_embeddings=tie_word_embeddings, + rope_parameters=rope_parameters, + bos_token_id=bos_token_id, + eos_token_id=eos_token_id, + pad_token_id=pad_token_id, + original_max_position_embeddings=original_max_position_embeddings, + sliding_window=sliding_window, + **kwargs, + ) + + +class Phi4MultimodalVisionMLP(SiglipMLP): + pass + + +def simple_eager_attention_forward( + module: nn.Module, + query_states: torch.Tensor, + key_states: torch.Tensor, + value_states: torch.Tensor, + attention_mask: torch.Tensor | None, + scaling: float, + dropout: float = 0.0, + **kwargs: Unpack[TransformersKwargs], +): + attn_weights = torch.matmul(query_states, key_states.transpose(2, 3)) * scaling + if attention_mask is not None: + attn_weights = attn_weights + attention_mask + + attn_weights = nn.functional.softmax(attn_weights, dim=-1, dtype=torch.float32).to(query_states.dtype) + attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training) + attn_output = torch.matmul(attn_weights, value_states) + attn_output = attn_output.transpose(1, 2).contiguous() + + return attn_output, attn_weights + + +class Phi4MultimodalVisionAttention(nn.Module): + def __init__(self, config: Phi4MultimodalVisionConfig): + super().__init__() + self.config = config + self.embed_dim = config.hidden_size + self.num_heads = config.num_attention_heads + self.head_dim = self.embed_dim // self.num_heads + self.scaling = self.head_dim**-0.5 + self.is_causal = True + self.attention_dropout = config.attention_dropout + + self.k_proj = nn.Linear(config.hidden_size, config.hidden_size) + self.v_proj = nn.Linear(config.hidden_size, config.hidden_size) + self.q_proj = nn.Linear(config.hidden_size, config.hidden_size) + self.out_proj = nn.Linear(config.hidden_size, config.hidden_size) + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor, torch.Tensor | None]: + """Input shape: Batch x Time x Channel""" + input_shape = hidden_states.shape[:-1] + hidden_shape = (*input_shape, -1, self.head_dim) + + query_states = self.q_proj(hidden_states).view(hidden_shape).transpose(1, 2) + key_states = self.k_proj(hidden_states).view(hidden_shape).transpose(1, 2) + value_states = self.v_proj(hidden_states).view(hidden_shape).transpose(1, 2) + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, simple_eager_attention_forward + ) + + attn_output, attn_weights = attention_interface( + self, + query_states, + key_states, + value_states, + attention_mask, + dropout=0.0 if not self.training else self.attention_dropout, + scaling=self.scaling, + **kwargs, + ) + + attn_output = attn_output.reshape(*input_shape, -1) + attn_output = self.out_proj(attn_output) + return attn_output, attn_weights + + +class Phi4MultimodalVisionEncoderLayer(SiglipEncoderLayer): + def __init__(self, config: Phi4MultimodalVisionConfig): + super().__init__(config) + self.self_attn = Phi4MultimodalVisionAttention(config) + self.mlp = Phi4MultimodalVisionMLP(config) + + +class Phi4MultimodalVisionEncoder(SiglipEncoder): + def __init__(self, config: Phi4MultimodalVisionConfig): + super().__init__(config) + self.layers = nn.ModuleList( + [Phi4MultimodalVisionEncoderLayer(config) for _ in range(config.num_hidden_layers)] + ) + + +class Phi4MultimodalVisionPreTrainedModel(SiglipPreTrainedModel): + config: Phi4MultimodalVisionConfig + base_model_prefix = "phi4_vision" + input_modalities = ("image",) + supports_gradient_checkpointing = True + + _no_split_modules = ["Phi4MultimodalVisionEncoderLayer"] + _supports_flash_attn = True + _supports_sdpa = True + _supports_flex_attn = True + + _can_record_outputs = { + "hidden_states": Phi4MultimodalVisionEncoderLayer, + "attentions": Phi4MultimodalVisionAttention, + } + + @torch.no_grad() + def _init_weights(self, module): + """Initialize the weights""" + if isinstance(module, Phi4MultimodalVisionEmbeddings): + width = ( + self.config.hidden_size + if isinstance(self.config, Phi4MultimodalVisionConfig) + else self.config.hidden_size + ) + init.normal_(module.position_embedding.weight, std=1 / np.sqrt(width)) + elif isinstance(module, nn.Embedding): + init.default_flax_embed_init_(module.weight) + elif isinstance(module, Phi4MultimodalVisionAttention): + init.normal_(module.q_proj.weight) + init.normal_(module.k_proj.weight) + init.normal_(module.v_proj.weight) + init.normal_(module.out_proj.weight) + init.zeros_(module.q_proj.bias) + init.zeros_(module.k_proj.bias) + init.zeros_(module.v_proj.bias) + init.zeros_(module.out_proj.bias) + elif isinstance(module, Phi4MultimodalVisionMLP): + init.normal_(module.fc1.weight) + init.normal_(module.fc2.weight) + init.normal_(module.fc1.bias, std=1e-6) + init.normal_(module.fc2.bias, std=1e-6) + elif isinstance(module, Phi4MultimodalVisionMultiheadAttentionPoolingHead): + init.normal_(module.probe) + init.normal_(module.attention.in_proj_weight) + init.zeros_(module.attention.in_proj_bias) + elif isinstance(module, (nn.Linear, nn.Conv2d)): + init.lecun_normal_(module.weight) + if module.bias is not None: + init.zeros_(module.bias) + elif isinstance(module, nn.LayerNorm): + init.zeros_(module.bias) + init.ones_(module.weight) + + +class Phi4MultimodalVisionEmbeddings(SiglipVisionEmbeddings): + def __init__(self, config: Phi4MultimodalVisionConfig): + nn.Module.__init__(self) + self.config = config + self.patch_size = config.patch_size + self.num_patches_per_side = config.image_size // self.patch_size + + self.patch_embedding = nn.Conv2d( + in_channels=config.num_channels, + out_channels=config.hidden_size, + kernel_size=self.patch_size, + stride=self.patch_size, + padding="valid", + ) + self.position_embedding = nn.Embedding(self.num_patches_per_side**2, config.hidden_size) + + def forward(self, pixel_values: torch.FloatTensor, patch_attention_mask: torch.BoolTensor) -> torch.Tensor: + batch_size, _, max_im_h, max_im_w = pixel_values.shape + + patch_embeds = self.patch_embedding(pixel_values) + embeddings = patch_embeds.flatten(2).transpose(1, 2) + + max_nb_patches_h, max_nb_patches_w = max_im_h // self.patch_size, max_im_w // self.patch_size + boundaries = torch.arange( + 1 / self.num_patches_per_side, 1.0, 1 / self.num_patches_per_side, device=pixel_values.device + ) + position_ids = torch.full( + size=(batch_size, max_nb_patches_h * max_nb_patches_w), fill_value=0, device=pixel_values.device + ) + + nb_patches_h = patch_attention_mask[:, :, 0].sum(dim=1) # (batch_size,) + nb_patches_w = patch_attention_mask[:, 0, :].sum(dim=1) # (batch_size,) + + step_h = 1.0 / nb_patches_h # (batch_size,) + step_w = 1.0 / nb_patches_w # (batch_size,) + + max_patches_h = patch_attention_mask.size(1) + max_patches_w = patch_attention_mask.size(2) + h_indices = torch.arange(max_patches_h, device=position_ids.device, dtype=torch.float32) + w_indices = torch.arange(max_patches_w, device=position_ids.device, dtype=torch.float32) + + fractional_coords_h = h_indices[None, :] * step_h[:, None] + fractional_coords_w = w_indices[None, :] * step_w[:, None] + + fractional_coords_h = torch.clamp(fractional_coords_h, max=(1.0 - 1e-6)) + fractional_coords_w = torch.clamp(fractional_coords_w, max=(1.0 - 1e-6)) + + fractional_coords_h = fractional_coords_h.to(pixel_values.dtype) + fractional_coords_w = fractional_coords_w.to(pixel_values.dtype) + + bucket_coords_h = torch.bucketize(fractional_coords_h, boundaries, right=True) + bucket_coords_w = torch.bucketize(fractional_coords_w, boundaries, right=True) + + pos_ids = bucket_coords_h[:, :, None] * self.num_patches_per_side + bucket_coords_w[:, None, :] + pos_ids = pos_ids.reshape(batch_size, -1) + + position_ids[patch_attention_mask.view(batch_size, -1)] = pos_ids[patch_attention_mask.view(batch_size, -1)] + + embeddings = embeddings + self.position_embedding(position_ids) + return embeddings + + +class Phi4MultimodalVisionMultiheadAttentionPoolingHead(SiglipMultiheadAttentionPoolingHead): + def __init__(self, config: Phi4MultimodalVisionConfig): + super().__init__(config) + self.mlp = Phi4MultimodalVisionMLP(config) + + def forward(self, hidden_state, attention_mask): + batch_size = hidden_state.shape[0] + probe = self.probe.repeat(batch_size, 1, 1) + + hidden_state = self.attention( + query=probe, key=hidden_state, value=hidden_state, key_padding_mask=~attention_mask + )[0] + + residual = hidden_state + hidden_state = self.layernorm(hidden_state) + hidden_state = residual + self.mlp(hidden_state) + + return hidden_state[:, 0] + + +class Phi4MultimodalVisionModel(Phi4MultimodalVisionPreTrainedModel): + config: Phi4MultimodalVisionConfig + main_input_name = "pixel_values" + + def __init__(self, config: Phi4MultimodalVisionConfig): + super().__init__(config) + self.config = config + + self.embeddings = Phi4MultimodalVisionEmbeddings(config) + self.encoder = Phi4MultimodalVisionEncoder(config) + self.post_layernorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps) + self.head = Phi4MultimodalVisionMultiheadAttentionPoolingHead(config) + + # Initialize weights and apply final processing + self.post_init() + + def get_input_embeddings(self) -> nn.Module: + return self.embeddings.patch_embedding + + @merge_with_config_defaults + @capture_outputs(tie_last_hidden_states=False) + def forward( + self, + pixel_values, + patch_attention_mask: torch.BoolTensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple | BaseModelOutputWithPooling: + batch_size = pixel_values.size(0) + if patch_attention_mask is None: + patch_attention_mask = torch.ones( + size=( + batch_size, + pixel_values.size(2) // self.config.patch_size, + pixel_values.size(3) // self.config.patch_size, + ), + dtype=torch.bool, + device=pixel_values.device, + ) + + hidden_states = self.embeddings(pixel_values=pixel_values, patch_attention_mask=patch_attention_mask) + + patch_attention_mask = patch_attention_mask.view(batch_size, -1) + attention_mask = create_bidirectional_mask( + config=self.config, + inputs_embeds=hidden_states, + attention_mask=patch_attention_mask, + ) + + encoder_outputs: BaseModelOutput = self.encoder( + inputs_embeds=hidden_states, + attention_mask=attention_mask, + **kwargs, + ) + + last_hidden_state = encoder_outputs.last_hidden_state + last_hidden_state = self.post_layernorm(last_hidden_state) + + pooled_output = self.head( + hidden_state=last_hidden_state, + attention_mask=patch_attention_mask, + ) + + return BaseModelOutputWithPooling( + last_hidden_state=last_hidden_state, + pooler_output=pooled_output, + ) + + +class Phi4MultimodalImageEmbedding(nn.Module): + """Image embedding.""" + + def __init__(self, config: Phi4MultimodalConfig): + super().__init__() + self.config = config + self.layer_idx = config.vision_config.feature_layer + self.crop_size = config.vision_config.crop_size + self.image_dim_out = config.vision_config.hidden_size + + n_patches = config.vision_config.image_size // config.vision_config.patch_size + if n_patches % 2 != 0: + self.img_processor_padding = nn.ReflectionPad2d((0, 1, 0, 1)) + n_patches += 1 + self.num_img_tokens = (n_patches // 2) ** 2 + + self.drop = nn.Dropout(config.embd_pdrop) + self.img_processor = Phi4MultimodalVisionModel._from_config(config.vision_config) + self.image_token_compression = nn.AvgPool2d(kernel_size=2, stride=2) + self.img_projection_up = nn.Linear(self.image_dim_out, config.hidden_size) + self.img_projection_down = nn.Linear(config.hidden_size, config.hidden_size) + self.global_img_feature_extensor = nn.Parameter(torch.zeros([1, 1, self.image_dim_out])) + self.sub_img_feature_extensor = nn.Parameter(torch.zeros([1, 1, 1, self.image_dim_out])) + + def get_img_features(self, img_embeds: torch.FloatTensor, attention_mask=None) -> torch.FloatTensor: + img_processor_output = self.img_processor( + img_embeds, patch_attention_mask=attention_mask, output_hidden_states=True + ) + img_feature = img_processor_output.hidden_states[self.layer_idx] + + patch_feature = img_feature + # reshape to 2D tensor + width = int(math.sqrt(patch_feature.size(1))) + patch_feature = patch_feature.view(-1, width, width, patch_feature.size(-1)) + # convert to NCHW + patch_feature = patch_feature.permute(0, 3, 1, 2) + if getattr(self, "img_processor_padding", None) is not None: + patch_feature = self.img_processor_padding(patch_feature) + patch_feature = self.image_token_compression(patch_feature) + # convert to NHWC + patch_feature = patch_feature.permute(0, 2, 3, 1) + patch_feature = patch_feature.view(-1, patch_feature.size(1) * patch_feature.size(2), patch_feature.size(-1)) + return patch_feature + + def forward( + self, + input_ids: torch.LongTensor, + inputs_embeds: torch.Tensor, + image_pixel_values: torch.FloatTensor, + image_sizes: torch.Tensor | None = None, + image_attention_mask: torch.Tensor | None = None, + ) -> torch.FloatTensor: + image_pixel_values = image_pixel_values.to(self.img_processor.embeddings.patch_embedding.weight.dtype) + + target_device = self.img_projection_up.bias.device + target_dtype = self.img_projection_up.bias.dtype + + batch_size = image_pixel_values.shape[0] + + img_features = self.get_img_features( + image_pixel_values.flatten(0, 1), + attention_mask=image_attention_mask.flatten(0, 1).to(dtype=bool, device=target_device), + ) + base_feat_size = int(np.sqrt(img_features.shape[1])) + img_features = img_features.view(batch_size, -1, base_feat_size**2, self.image_dim_out) + image_sizes = image_sizes.view(-1, 2) + + output_imgs = [] + for idx in range(batch_size): + height, width = image_sizes[idx] + height_ratio = height // self.crop_size + width_ratio = width // self.crop_size + area_ratio = height_ratio * width_ratio + + global_img = img_features[idx, :1] + global_img = global_img.reshape(1, base_feat_size, base_feat_size, self.image_dim_out).contiguous() + temporary_extensor = self.sub_img_feature_extensor.repeat(1, base_feat_size, 1, 1) + global_img = torch.cat([global_img, temporary_extensor], dim=2).reshape(1, -1, self.image_dim_out) + + sub_img = img_features[idx, 1:] + sub_img = sub_img[:area_ratio] + sub_img = ( + sub_img.reshape(height_ratio, width_ratio, base_feat_size, base_feat_size, self.image_dim_out) + .transpose(1, 2) + .reshape(1, height_ratio * base_feat_size, width_ratio * base_feat_size, self.image_dim_out) + .contiguous() + ) + + if image_attention_mask is not None: + reshaped_image_attention_mask = ( + image_attention_mask[idx, 1 : area_ratio + 1, 0::2, 0::2] + .reshape(height_ratio, width_ratio, base_feat_size, base_feat_size) + .transpose(1, 2) + .reshape(1, height_ratio * base_feat_size, width_ratio * base_feat_size) + ) + useful_height = int(reshaped_image_attention_mask[0, :, 0].sum().item()) + useful_width = int(reshaped_image_attention_mask[0, 0, :].sum().item()) + sub_img = sub_img[:, :useful_height, :useful_width] + temporary_extensor = self.sub_img_feature_extensor.repeat(1, useful_height, 1, 1) + else: + temporary_extensor = self.sub_img_feature_extensor.repeat(1, height_ratio * base_feat_size, 1, 1) + + sub_img = torch.cat([sub_img, temporary_extensor], dim=2).reshape(1, -1, self.image_dim_out) + + # Merge global and sub + output_imgs.append(torch.cat([sub_img, self.global_img_feature_extensor, global_img], dim=1)) + + img_set_tensor = [] + for output_img in output_imgs: + output_img = output_img.to(device=target_device, dtype=target_dtype) + img_feature_proj = self.img_projection_up(output_img) + img_feature_proj = nn.functional.gelu(img_feature_proj) + img_feature_proj = self.img_projection_down(img_feature_proj) + img_set_tensor.append(img_feature_proj) + + merged_img_set_tensor = torch.cat(img_set_tensor, dim=1).squeeze(0) + merged_img_set_tensor = merged_img_set_tensor.to(dtype=inputs_embeds.dtype, device=inputs_embeds.device) + + with torch.no_grad(): + positions_tuple = torch.nonzero(input_ids == self.config.vision_config.image_token_id, as_tuple=True) + + # Temporarily disable autocast to avoid issue on bf16 tensors + # Ref: https://github.com/pytorch/pytorch/issues/132715 + with maybe_autocast(device_type=inputs_embeds.device.type, enabled=False): + image_embeds = inputs_embeds.index_put( + indices=positions_tuple, values=merged_img_set_tensor, accumulate=False + ) + + image_embeds = self.drop(image_embeds) + + return image_embeds + + +########################################################## AUDIO ############################################# + + +class Phi4MultimodalAudioMLP(nn.Module): + def __init__(self, config: Phi4MultimodalAudioConfig): + super().__init__() + self.layer_norm = nn.LayerNorm(config.hidden_size) + self.act_fn = ACT2FN[config.activation] + self.gate_up_proj = nn.Linear(config.hidden_size, config.intermediate_size * 2) + self.down_proj = nn.Linear(config.intermediate_size, config.hidden_size) + self.dropout = nn.Dropout(config.dropout_rate) + + def forward(self, hidden_states): + hidden_states = self.layer_norm(hidden_states) + up_states = self.gate_up_proj(hidden_states) + up_states, gate = up_states.chunk(2, dim=-1) + up_states = up_states * self.act_fn(gate) + up_states = self.dropout(up_states) + hidden_states = self.down_proj(up_states) + out = self.dropout(hidden_states) + + return out + + +class Phi4MultimodalAudioAttention(nn.Module): + def __init__(self, config: Phi4MultimodalAudioConfig): + super().__init__() + self.config = config + self.head_dim = getattr(config, "head_dim", config.hidden_size // config.num_attention_heads) + self.scaling = self.head_dim**-0.5 + self.attention_dropout = config.dropout_rate + self.is_causal = True + + self.q_proj = nn.Linear(config.hidden_size, config.num_attention_heads * self.head_dim, bias=True) + self.k_proj = nn.Linear(config.hidden_size, config.num_attention_heads * self.head_dim, bias=True) + self.v_proj = nn.Linear(config.hidden_size, config.num_attention_heads * self.head_dim, bias=True) + self.o_proj = nn.Linear(config.num_attention_heads * self.head_dim, config.hidden_size, bias=True) + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.Tensor, + **kwargs, + ): + input_shape = hidden_states.shape[:-1] + hidden_shape = (*input_shape, -1, self.head_dim) + + query_states = self.q_proj(hidden_states).view(hidden_shape).transpose(1, 2) + key_states = self.k_proj(hidden_states).view(hidden_shape).transpose(1, 2) + value_states = self.v_proj(hidden_states).view(hidden_shape).transpose(1, 2) + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, simple_eager_attention_forward + ) + + attn_output, _ = attention_interface( + self, + query_states, + key_states, + value_states, + attention_mask, + dropout=0.0 if not self.training else self.attention_dropout, + scaling=self.scaling, + **kwargs, + ) + + attn_output = attn_output.reshape(*input_shape, -1).contiguous() + attn_output = self.o_proj(attn_output) + return attn_output + + +class Phi4MultimodalAudioDepthWiseSeparableConv1d(nn.Module): + def __init__(self, config: Phi4MultimodalAudioConfig, padding: int = 0): + super().__init__() + self.dw_conv = nn.Conv1d( + config.hidden_size, + config.hidden_size * config.depthwise_multiplier, + config.kernel_size, + 1, + padding=padding, + groups=config.hidden_size, + ) + self.pw_conv = nn.Conv1d( + config.hidden_size * config.depthwise_multiplier, config.depthwise_separable_out_channel, 1, 1, 0 + ) + + def forward(self, hidden_states): + return self.pw_conv(self.dw_conv(hidden_states)) + + +class Phi4MultimodalAudioGluPointWiseConv(nn.Module): + def __init__(self, config: Phi4MultimodalAudioConfig): + super().__init__() + self.config = config + self.output_dim = config.ext_pw_out_channel + + self.ext_pw_conv_1d = nn.Conv1d(config.hidden_size, config.ext_pw_out_channel * 2, kernel_size=1, stride=1) + self.glu_act = ACT2FN[config.conv_glu_type] + self.b1 = nn.Parameter(torch.zeros(1, config.ext_pw_out_channel, 1)) + self.b2 = nn.Parameter(torch.zeros(1, config.ext_pw_out_channel, 1)) + + def forward(self, hidden_states): + # we assume the input always has the #channel (#dim) in the last dimension of the + # tensor, so need to switch the dimension first for 1D-Conv case + hidden_states = hidden_states.permute([0, 2, 1]) + hidden_states = self.ext_pw_conv_1d(hidden_states) + out = hidden_states[:, 0 : self.output_dim, :] + self.b1 + out = out * self.glu_act(hidden_states[:, self.output_dim : self.output_dim * 2, :] + self.b2) + return out.permute([0, 2, 1]) + + +class Phi4MultimodalAudioConvModule(nn.Module): + def __init__(self, config: Phi4MultimodalAudioConfig): + super().__init__() + self.config = config + self.kernel_size = config.kernel_size + + self.layer_norm = nn.LayerNorm(config.hidden_size) + self.glu = Phi4MultimodalAudioGluPointWiseConv(config) + self.dw_sep_conv_1d = Phi4MultimodalAudioDepthWiseSeparableConv1d(config, padding=config.kernel_size - 1) + self.act = ACT2FN[config.conv_activation] + self.ext_pw_conv_1d = nn.Conv1d(config.hidden_size, config.ext_pw_out_channel, kernel_size=1, stride=1) + self.dropout = nn.Dropout(config.dropout_rate) + + def forward(self, hidden_states: torch.Tensor): + hidden_states = self.glu(self.layer_norm(hidden_states)) + hidden_states = self.dw_sep_conv_1d(hidden_states.permute([0, 2, 1])) + + if self.kernel_size > 1: + hidden_states = hidden_states[:, :, : -(self.kernel_size - 1)] + + hidden_states = self.act(hidden_states) + hidden_states = self.ext_pw_conv_1d(hidden_states) + out = self.dropout(hidden_states.permute([0, 2, 1])) + return out + + +class Phi4MultimodalAudioConformerEncoderLayer(nn.Module): + def __init__(self, config: Phi4MultimodalAudioConfig): + super().__init__() + + self.feed_forward_in = Phi4MultimodalAudioMLP(config) + self.self_attn = Phi4MultimodalAudioAttention(config) + self.conv = Phi4MultimodalAudioConvModule(config) + self.feed_forward_out = Phi4MultimodalAudioMLP(config) + self.layer_norm_att = nn.LayerNorm(config.hidden_size) + self.layer_norm = nn.LayerNorm(config.hidden_size) + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.Tensor, + ): + residual = hidden_states + 0.5 * self.feed_forward_in(hidden_states) + hidden_states = self.layer_norm_att(residual) + + hidden_states = residual + self.self_attn(hidden_states, attention_mask) + hidden_states = hidden_states + self.conv(hidden_states) + hidden_states = hidden_states + 0.5 * self.feed_forward_out(hidden_states) + + out = self.layer_norm(hidden_states) + + return out + + +class Phi4MultimodalAudioNemoConvSubsampling(torch.nn.Module): + def __init__(self, config: Phi4MultimodalAudioConfig): + super().__init__() + self.subsampling_factor = config.time_reduction + self.sampling_num = int(math.log2(self.subsampling_factor)) + self.act_fn = ACT2FN[config.nemo_activation] + conv_channels = config.nemo_conv_channels + + layers = [ + nn.Conv2d(1, conv_channels, kernel_size=3, stride=2, padding=1), + self.act_fn, + ] + for _ in range(self.sampling_num - 1): + layers.extend( + [ + nn.Conv2d(conv_channels, conv_channels, kernel_size=3, stride=2, padding=1, groups=conv_channels), + nn.Conv2d(conv_channels, conv_channels, kernel_size=1, stride=1, padding=0, groups=1), + self.act_fn, + ] + ) + + # Aggregate the layers + self.conv = torch.nn.Sequential(*layers) + self.out = torch.nn.Linear(conv_channels * config.nemo_final_size, config.hidden_size) + + def forward(self, hidden_states: torch.Tensor, mask: torch.Tensor | None): + # Unsqueeze Channel Axis + hidden_states = hidden_states.unsqueeze(1) + hidden_states = self.conv(hidden_states) + + # Flatten Channel and Frequency Axes + b, _, t, _ = hidden_states.size() + hidden_states = self.out(hidden_states.transpose(1, 2).reshape(b, t, -1)) + + if mask is None: + return hidden_states, None + + max_audio_length = hidden_states.shape[1] + feature_lens = mask.sum(1) + padding_length = torch.ceil(feature_lens / self.subsampling_factor) + arange_ = torch.arange(0, max_audio_length, device=hidden_states.device) + pad_mask = arange_.expand(padding_length.size(0), -1) < padding_length.unsqueeze(1) + return hidden_states, pad_mask.unsqueeze(1) + + +class Phi4MultimodalAudioRelativeAttentionBias(nn.Module): + def __init__(self, config: Phi4MultimodalAudioConfig): + super().__init__() + + self.max_distance = config.bias_max_distance + self.symmetric = config.bias_symmetric + self.num_buckets = self.max_distance + if not config.bias_symmetric: + self.num_buckets *= 2 + self.bias_values = nn.Embedding(self.num_buckets, config.num_attention_heads) + + def forward(self, x): + # instantiate bias compatible with shape of x + max_pos = x.size(1) + context_position = torch.arange(max_pos, device=x.device, dtype=torch.long)[:, None] + memory_position = torch.arange(max_pos, device=x.device, dtype=torch.long)[None, :] + relative_position = memory_position - context_position + # clipping to a maximum distance using ops that play well with ONNX export + relative_position = relative_position.masked_fill(relative_position < -self.max_distance, -self.max_distance) + relative_position = relative_position.masked_fill( + relative_position > self.max_distance - 1, self.max_distance - 1 + ) + + # mapping from relative position to index in the bias parameter + bias_idx = relative_position + bias_idx = bias_idx.abs() if self.symmetric else bias_idx + self.num_buckets // 2 + + att_bias = self.bias_values(bias_idx) + att_bias = att_bias.permute(2, 0, 1).unsqueeze(0) + + return att_bias + + +class Phi4MultimodalAudioMeanVarianceNormLayer(nn.Module): + def __init__(self, config: Phi4MultimodalAudioConfig): + super().__init__() + self.register_buffer("global_mean", torch.zeros(config.input_size)) + self.register_buffer("global_invstd", torch.ones(config.input_size)) + + def forward(self, x): + return (x - self.global_mean) * self.global_invstd + + +@auto_docstring +class Phi4MultimodalAudioPreTrainedModel(PreTrainedModel): + config: Phi4MultimodalAudioConfig + input_modalities = "audio" + supports_gradient_checkpointing = True + _no_split_modules = ["Phi4MultimodalAudioConformerEncoderLayer"] + _supports_flash_attn = True + _supports_sdpa = True + _supports_flex_attn = True + + @torch.no_grad() + def _init_weights(self, module): + super()._init_weights(module) + if isinstance(module, Phi4MultimodalAudioGluPointWiseConv): + init.zeros_(module.b1) + init.zeros_(module.b2) + elif isinstance(module, Phi4MultimodalAudioMeanVarianceNormLayer): + init.zeros_(module.global_mean) + init.ones_(module.global_invstd) + + +class Phi4MultimodalAudioModel(Phi4MultimodalAudioPreTrainedModel): + def __init__(self, config: Phi4MultimodalAudioConfig): + super().__init__(config) + self.config = config + + self.encoder_embedding = Phi4MultimodalAudioMeanVarianceNormLayer(config) + self.embed = Phi4MultimodalAudioNemoConvSubsampling(config) + self.relative_attention_bias_layer = Phi4MultimodalAudioRelativeAttentionBias(config) + self.encoders = nn.ModuleList( + [Phi4MultimodalAudioConformerEncoderLayer(config) for _ in range(config.num_blocks)] + ) + self.gradient_checkpointing = False + + # Initialize weights and apply final processing + self.post_init() + + def _streaming_mask(self, seq_len, batch_size, chunk_size, left_chunk): + # Create mask matrix for streaming + # S stores start index. if chunksize is 18, s is [0,18,36,....] + chunk_start_idx = np.arange(0, seq_len, chunk_size) + # avoid randomness when run evaluation or decoding + if self.training and np.random.rand() > 0.5: + # Either first or last chunk is not complete. + # If only the last one is not complete, EOS is not effective + chunk_start_idx = seq_len - chunk_start_idx + chunk_start_idx = chunk_start_idx[::-1] + chunk_start_idx = chunk_start_idx[:-1] + chunk_start_idx = np.insert(chunk_start_idx, 0, 0) + + enc_streaming_mask = ( + adaptive_enc_mask(seq_len, chunk_start_idx, left_window=left_chunk) + .unsqueeze(0) + .expand([batch_size, -1, -1]) + ) + return enc_streaming_mask + + def forward_embeddings(self, hidden_states, masks): + """Forwarding the inputs through the top embedding layers""" + seq_len = math.ceil(hidden_states.shape[1] / self.config.time_reduction) + if seq_len <= 0: + raise ValueError( + f"The sequence length after time reduction is invalid: {seq_len}. Your input feature is too short." + ) + + batch_size = hidden_states.shape[0] + + enc_streaming_mask = self._streaming_mask(seq_len, batch_size, self.config.chunk_size, self.config.left_chunk) + enc_streaming_mask = enc_streaming_mask.to(hidden_states.device) + + hidden_states, masks = self.embed(hidden_states, masks) + + streaming_mask = enc_streaming_mask + if streaming_mask is not None and masks is not None: + hs_mask = masks & streaming_mask + elif masks is not None: + hs_mask = masks + else: + hs_mask = streaming_mask + + return hidden_states, hs_mask, masks + + def calculate_hs_mask(self, hidden_states, device, mask): + max_audio_length = hidden_states.shape[1] + batch_size = hidden_states.shape[0] + enc_streaming_mask = self._streaming_mask( + max_audio_length, batch_size, self.config.chunk_size, self.config.left_chunk + ) + enc_streaming_mask = enc_streaming_mask.to(device) + if mask is None: + return enc_streaming_mask + + feature_lens = mask.sum(1) + padding_length = feature_lens + pad_mask = torch.arange(0, max_audio_length, device=device).expand( + padding_length.size(0), -1 + ) < padding_length.unsqueeze(1) + pad_mask = pad_mask.unsqueeze(1) + pad_mask = pad_mask & enc_streaming_mask + return pad_mask + + def forward(self, hidden_states: torch.Tensor, mask: torch.Tensor | None, **kwargs): + hidden_states = self.encoder_embedding(hidden_states) + hidden_states, hs_mask, mask = self.forward_embeddings(hidden_states, mask) + + unfolded = False + bs, seq_len, _ = hidden_states.shape + max_seq_len = 500 # maximum position for absolute positional encoding + if seq_len > max_seq_len: + # audio sequence is longer than max_seq_len, unfold it into chunks of max_seq_len + unfolded = True + # the unfold op will drop residual frames, pad it to the multiple of max_seq_len + if seq_len % max_seq_len > 0: + chunk_pad_size = max_seq_len - (seq_len % max_seq_len) + else: + chunk_pad_size = 0 + if chunk_pad_size > 0: + hidden_states_pad = F.pad(hidden_states, (0, 0, 0, chunk_pad_size), "constant", 0) + hidden_states = hidden_states_pad.to(hidden_states.device) + + hidden_states = unfold_tensor(hidden_states, max_seq_len) + masks_unfold = None + if mask is not None: + # revise hs_mask here because the previous calculated hs_mask did not consider extra pad + subsampled_pad_mask = mask.squeeze(1) # [bz, subsampled_unmask_seq_len] + extra_padded_subsamlped_pad_mask = F.pad( + subsampled_pad_mask, (0, chunk_pad_size), "constant", False + ) # extra padding to the pad mask + extra_padded_subsamlped_pad_mask = extra_padded_subsamlped_pad_mask.unsqueeze(-1).float() + masks_unfold = unfold_tensor( + extra_padded_subsamlped_pad_mask, max_seq_len + ) # unfold the pad mask like we did to the input tensor + masks_unfold = masks_unfold.squeeze(-1).bool() # unfold op does not support bool tensor + hs_mask = self.calculate_hs_mask( + hidden_states, hidden_states.device, masks_unfold + ) # calculate hs_mask based on the unfolded pad mask + + relative_attention_bias = self.relative_attention_bias_layer(hidden_states) + attention_mask = hs_mask.unsqueeze(1) + relative_attention_bias + + for layer in self.encoders: + hidden_states = layer(hidden_states, attention_mask) + + if unfolded: + embed_dim = hidden_states.shape[-1] + hidden_states = hidden_states.reshape(bs, -1, embed_dim) + # if we ever padded before unfolding, we need to remove the padding + if chunk_pad_size > 0: + hidden_states = hidden_states[:, :-chunk_pad_size, :] + + return hidden_states + + +def unfold_tensor(tensor, max_seq_len): + """ + For a given tensor with shape of (N, T, D), if sequence length T is longer than max_seq_len, + this function unfold it to a (NT', max_seq_len, D) where T' is T // max_seq_len. + Args: + tensor: N, T, D + """ + _, _, D = tensor.shape + tensor = tensor.transpose(-1, -2) + # N x D x 1 x T => N x (D x max_seq_len) x T' + tensor = F.unfold(tensor[..., None, :], kernel_size=(1, max_seq_len), stride=(1, max_seq_len)) + + new_bsz, _, slen = tensor.shape + tensor = tensor.view(new_bsz, -1, max_seq_len, slen) + tensor = tensor.permute(0, 3, 2, 1) + tensor = tensor.view(-1, max_seq_len, D).contiguous() + return tensor + + +def adaptive_enc_mask(x_len, chunk_start_idx, left_window=0, right_window=0): + """ + The function is very important for Transformer Transducer Streaming mode + Args: + xs_len (int): sequence length + chunk_start_idx (list): first idx of each chunk, such as [0,18,36,48]. It also supports adaptive chunk size [0,10,15,45] + left_window (int): how many left chunks can be seen + right_window (int): how many right chunks can be seen. It is used for chunk overlap model. + Returns: + mask (torch.Tensor): a mask tensor for streaming model + """ + chunk_start_idx = torch.Tensor(chunk_start_idx).long() + start_pad = torch.nn.functional.pad( + chunk_start_idx, (1, 0) + ) # append 0 to the beginning, so it becomes [0, 0, 18, 36, 48] + end_pad = torch.nn.functional.pad( + chunk_start_idx, (0, 1), value=x_len + ) # append x_len to the end, so it becomes [0,18,36,48, x_len] + seq_range = torch.arange(0, x_len).unsqueeze(-1) + idx = ((seq_range < end_pad) & (seq_range >= start_pad)).nonzero()[:, 1] + seq_range_expand = torch.arange(0, x_len).unsqueeze(0).expand(x_len, -1) + idx_left = idx - left_window + idx_left[idx_left < 0] = 0 + boundary_left = start_pad[idx_left] + mask_left = seq_range_expand >= boundary_left.unsqueeze(-1) + idx_right = idx + right_window + idx_right[idx_right > len(chunk_start_idx)] = len(chunk_start_idx) + boundary_right = end_pad[idx_right] + mask_right = seq_range_expand < boundary_right.unsqueeze(-1) + return mask_left & mask_right + + +class Phi4MultimodalAudioEmbedding(nn.Module): + def __init__(self, config: Phi4MultimodalConfig): + super().__init__() + self.config = config + self.layer_idx = config.audio_config.feature_layer + + self.drop = nn.Dropout(config.embd_pdrop) + self.encoder = Phi4MultimodalAudioModel._from_config(config.audio_config) + self.up_proj_for_speech = nn.Linear( + config.audio_config.hidden_size * config.audio_config.downsample_rate, config.hidden_size + ) + self.down_proj_for_speech = nn.Linear(config.hidden_size, config.hidden_size) + self.up_proj_for_vision_speech = nn.Linear( + config.audio_config.hidden_size * config.audio_config.downsample_rate, config.hidden_size + ) + self.down_proj_for_vision_speech = nn.Linear(config.hidden_size, config.hidden_size) + + def forward( + self, + input_ids: torch.LongTensor, + inputs_embeds: torch.Tensor, + audio_input_features: torch.FloatTensor, + audio_embed_sizes=None, + audio_attention_mask=None, + audio_projection_mode="speech", + ) -> torch.FloatTensor: + with torch.no_grad(): + positions_tuple = torch.nonzero(input_ids == self.config.audio_config.audio_token_id, as_tuple=True) + + up_proj = self.up_proj_for_speech if audio_projection_mode == "speech" else self.up_proj_for_vision_speech + down_proj = ( + self.down_proj_for_speech if audio_projection_mode == "speech" else self.down_proj_for_vision_speech + ) + + target_device = up_proj.bias.device + target_dtype = up_proj.bias.dtype + + audio_input_features = audio_input_features.to(device=target_device, dtype=target_dtype) + + audio_encoder_hidden_states = self.encoder(audio_input_features, audio_attention_mask) + audio_encoder_hidden_states = up_proj(audio_encoder_hidden_states) + audio_encoder_hidden_states = nn.functional.gelu(audio_encoder_hidden_states) + audio_embeds = down_proj(audio_encoder_hidden_states) + + merged_audio_embeds = torch.cat( + [audio_embeds[i, : audio_embed_sizes[i], :] for i in range(len(audio_embed_sizes))], dim=0 + ) + merged_audio_embeds = merged_audio_embeds.to(dtype=inputs_embeds.dtype, device=inputs_embeds.device) + # Temporarily disable autocast to avoid issue on bf16 tensors + # Ref: https://github.com/pytorch/pytorch/issues/132715 + with maybe_autocast(device_type=inputs_embeds.device.type, enabled=False): + audio_embeds = inputs_embeds.index_put( + indices=positions_tuple, values=merged_audio_embeds, accumulate=False + ) + + audio_embeds = self.drop(audio_embeds) + + return audio_embeds + + +#################################################### TEXT #################################################### + + +class Phi4MultimodalRMSNorm(Phi3RMSNorm): + pass + + +class Phi4MultimodalDecoderLayer(Phi3DecoderLayer): + pass + + +class Phi4MultimodalFeatureEmbedding(nn.Module): + """Image-audio embedding.""" + + def __init__(self, config: Phi4MultimodalConfig) -> None: + super().__init__() + self.config = config + self.image_token_id = config.vision_config.image_token_id + self.audio_token_id = config.audio_config.audio_token_id + self.image_embed = Phi4MultimodalImageEmbedding(config) + self.audio_embed = Phi4MultimodalAudioEmbedding(config) + + def forward( + self, + input_ids: torch.LongTensor, + inputs_embeds: torch.Tensor, + image_pixel_values: torch.FloatTensor | None = None, + audio_input_features: torch.FloatTensor | None = None, + image_sizes=None, + image_attention_mask=None, + audio_embed_sizes=None, + audio_attention_mask=None, + ) -> torch.FloatTensor: + with torch.no_grad(): + image_position_mask = (input_ids == self.config.vision_config.image_token_id).unsqueeze(-1) + non_image_position_mask = ~image_position_mask + + image_embeds = None + audio_embeds = None + if image_pixel_values is not None and (input_ids == self.image_token_id).any(): + image_embeds = self.image_embed( + input_ids, + inputs_embeds, + image_pixel_values=image_pixel_values, + image_sizes=image_sizes, + image_attention_mask=image_attention_mask, + ) + if audio_input_features is not None and (input_ids == self.audio_token_id).any(): + audio_projection_mode = "vision" if image_pixel_values is not None else "speech" + audio_embeds = self.audio_embed( + input_ids, + inputs_embeds, + audio_input_features=audio_input_features, + audio_embed_sizes=audio_embed_sizes, + audio_attention_mask=audio_attention_mask, + audio_projection_mode=audio_projection_mode, + ) + + # merge image and audio + if image_embeds is not None and audio_embeds is not None: + inputs_embeds = image_embeds * image_position_mask + audio_embeds * non_image_position_mask + elif image_embeds is not None: + inputs_embeds = image_embeds + elif audio_embeds is not None: + inputs_embeds = audio_embeds + + return inputs_embeds + + +class Phi4MultimodalPreTrainedModel(Phi3PreTrainedModel): + input_modalities = ("image", "audio", "text") + + @torch.no_grad() + def _init_weights(self, module): + PreTrainedModel._init_weights(self, module) + if isinstance(module, Phi4MultimodalImageEmbedding): + init.zeros_(module.global_img_feature_extensor) + init.zeros_(module.sub_img_feature_extensor) + + +class Phi4MultimodalModel(Phi3Model): + def __init__(self, config: Phi4MultimodalConfig): + super().__init__(config) + self.padding_idx = config.pad_token_id + self.vocab_size = config.vocab_size + + self.embed_tokens = nn.Embedding(config.vocab_size, config.hidden_size, self.padding_idx) + self.embed_dropout = nn.Dropout(config.embd_pdrop) + + self.embed_tokens_extend = Phi4MultimodalFeatureEmbedding(config) + + self.layers = nn.ModuleList( + [Phi4MultimodalDecoderLayer(config, layer_idx) for layer_idx in range(config.num_hidden_layers)] + ) + self.norm = Phi4MultimodalRMSNorm(config.hidden_size, eps=config.rms_norm_eps) + + self.gradient_checkpointing = False + # Initialize weights and apply final processing + self.post_init() + + @merge_with_config_defaults + @capture_outputs + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.Tensor | None = None, + position_ids: torch.LongTensor | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.FloatTensor | None = None, + image_pixel_values: torch.FloatTensor | None = None, + image_sizes: torch.LongTensor | None = None, + image_attention_mask=None, + audio_input_features: torch.FloatTensor | None = None, + audio_embed_sizes=None, + audio_attention_mask=None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + cache_position: torch.LongTensor | None = None, + **kwargs, + ) -> tuple | BaseModelOutputWithPast: + r""" + image_pixel_values (`torch.FloatTensor`, *optional*): + If the input contains images, these correspond to the pixel values after transformations (as returned by + the Processor) + image_sizes (`torch.LongTensor`, *optional*): + If the input contains images, these correspond to size of each image. + image_attention_mask (`torch.LongTensor`, *optional*): + Attention mask for the images. + audio_input_features (`torch.FloatTensor`, *optional*): + If the input contains audio samples, these correspond to the values after transformation (as returned by + the Processor). + audio_embed_sizes (`torch.Tensor`, *optional*): + Size of the audio inputs. + audio_attention_mask (`torch.Tensor, *optional*): + Attention mask for the audio inputs. + """ + if (input_ids is None) ^ (inputs_embeds is not None): + raise ValueError("You must specify exactly one of input_ids or inputs_embeds") + if use_cache and past_key_values is None: + past_key_values = DynamicCache(config=self.config) + + if inputs_embeds is None: + inputs_embeds = self.embed_tokens(input_ids) + inputs_embeds = self.embed_tokens_extend( + input_ids, + inputs_embeds, + image_pixel_values=image_pixel_values, + audio_input_features=audio_input_features, + image_sizes=image_sizes, + image_attention_mask=image_attention_mask, + audio_embed_sizes=audio_embed_sizes, + audio_attention_mask=audio_attention_mask, + ) + + if cache_position is None: + past_seen_tokens = past_key_values.get_seq_length() if past_key_values is not None else 0 + cache_position = torch.arange( + past_seen_tokens, past_seen_tokens + inputs_embeds.shape[1], device=inputs_embeds.device + ) + if position_ids is None: + position_ids = cache_position.unsqueeze(0) + + mask_function = create_causal_mask if self.config.sliding_window is None else create_sliding_window_causal_mask + causal_mask = mask_function( + config=self.config, + inputs_embeds=inputs_embeds, + attention_mask=attention_mask, + cache_position=cache_position, + past_key_values=past_key_values, + position_ids=position_ids, + ) + + hidden_states = inputs_embeds + position_embeddings = self.rotary_emb(hidden_states, position_ids=position_ids) + + for decoder_layer in self.layers: + hidden_states = decoder_layer( + hidden_states, + attention_mask=causal_mask, + position_ids=position_ids, + past_key_values=past_key_values, + use_cache=use_cache, + cache_position=cache_position, + position_embeddings=position_embeddings, + **kwargs, + ) + + hidden_states = self.norm(hidden_states) + return BaseModelOutputWithPast( + last_hidden_state=hidden_states, + past_key_values=past_key_values if use_cache else None, + ) + + +class Phi4MultimodalForCausalLM(Phi3ForCausalLM): + _tied_weights_keys = {"lm_head.weight": "model.embed_tokens.weight"} + + def __init__(self, config): + super().__init__(config) + self.model = Phi4MultimodalModel(config) + self.vocab_size = config.vocab_size + self.lm_head = nn.Linear(config.hidden_size, config.vocab_size, bias=False) + + # Initialize weights and apply final processing + self.post_init() + + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.Tensor | None = None, + position_ids: torch.LongTensor | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.FloatTensor | None = None, + image_pixel_values: torch.FloatTensor | None = None, + image_sizes: torch.LongTensor | None = None, + image_attention_mask=None, + audio_input_features: torch.FloatTensor | None = None, + audio_embed_sizes=None, + audio_attention_mask=None, + labels: torch.LongTensor | None = None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + cache_position: torch.LongTensor | None = None, + logits_to_keep: int | torch.Tensor = 0, + **kwargs, + ) -> CausalLMOutputWithPast: + r""" + image_pixel_values (`torch.FloatTensor`, *optional*): + If the input contains images, these correspond to the pixel values after transformations (as returned by + the Processor) + image_sizes (`torch.LongTensor`, *optional*): + If the input contains images, these correspond to size of each image. + image_attention_mask (`torch.LongTensor`, *optional*): + Attention mask for the images. + audio_input_features (`torch.FloatTensor`, *optional*): + If the input contains audio samples, these correspond to the values after transformation (as returned by + the Processor). + audio_embed_sizes (`torch.Tensor`, *optional*): + Size of the audio inputs. + audio_attention_mask (`torch.Tensor, *optional*): + Attention mask for the audio inputs. + labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Labels for computing the masked language modeling loss. Indices should either be in `[0, ..., + config.vocab_size]` or -100 (see `input_ids` docstring). Tokens with indices set to `-100` are ignored + (masked), the loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]`. + + Example: + ```python + >>> from transformers import AutoTokenizer, Phi4MultimodalForCausalLM + >>> model = Phi4MultimodalForCausalLM.from_pretrained("TBA") + >>> tokenizer = AutoTokenizer.from_pretrained("TBA") + >>> prompt = "This is an example script ." + >>> inputs = tokenizer(prompt, return_tensors="pt") + >>> # Generate + >>> generate_ids = model.generate(inputs.input_ids, max_length=30) + >>> tokenizer.batch_decode(generate_ids, skip_special_tokens=True, clean_up_tokenization_spaces=False)[0] + 'This is an example script .\n Certainly! Below is a sample script that demonstrates a simple task, such as calculating the sum' + ```""" + + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + + # decoder outputs consists of (dec_features, layer_state, dec_hidden, dec_attn) + outputs: BaseModelOutputWithPast = self.model( + input_ids=input_ids, + attention_mask=attention_mask, + position_ids=position_ids, + past_key_values=past_key_values, + inputs_embeds=inputs_embeds, + image_pixel_values=image_pixel_values, + image_sizes=image_sizes, + image_attention_mask=image_attention_mask, + audio_input_features=audio_input_features, + audio_embed_sizes=audio_embed_sizes, + audio_attention_mask=audio_attention_mask, + use_cache=use_cache, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + cache_position=cache_position, + **kwargs, + ) + + hidden_states = outputs.last_hidden_state + # Only compute necessary logits, and do not upcast them to float if we are not computing the loss + slice_indices = slice(-logits_to_keep, None) if isinstance(logits_to_keep, int) else logits_to_keep + logits = self.lm_head(hidden_states[:, slice_indices, :]) + + loss = None + if labels is not None: + loss = self.loss_function(logits, labels, self.vocab_size) + + return CausalLMOutputWithPast( + loss=loss, + logits=logits, + past_key_values=outputs.past_key_values, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + ) + + def prepare_inputs_for_generation( + self, + input_ids, + past_key_values=None, + attention_mask=None, + inputs_embeds=None, + image_pixel_values=None, + image_sizes=None, + image_attention_mask=None, + audio_input_features=None, + audio_embed_sizes=None, + audio_attention_mask=None, + cache_position=None, + position_ids=None, + use_cache=True, + logits_to_keep=0, + **kwargs, + ): + # Overwritten -- this model may need to switch between short and long rope, invalidating the cache in the + # process + + # When the first time input length reached long and short factor switching point, enforce re-compute cache + # It will cause downside of slower at this single token position, however, better than current failure. + if ( + past_key_values + and self.config.rope_parameters + and input_ids.shape[1] >= self.config.original_max_position_embeddings + 1 + ): + past_length = cache_position[0] + if past_length <= self.config.original_max_position_embeddings: + past_key_values = None + + model_inputs = super().prepare_inputs_for_generation( + input_ids=input_ids, + past_key_values=past_key_values, + attention_mask=attention_mask, + inputs_embeds=inputs_embeds, + image_pixel_values=image_pixel_values, + image_sizes=image_sizes, + image_attention_mask=image_attention_mask, + audio_input_features=audio_input_features, + audio_embed_sizes=audio_embed_sizes, + audio_attention_mask=audio_attention_mask, + cache_position=cache_position, + position_ids=position_ids, + use_cache=use_cache, + logits_to_keep=logits_to_keep, + **kwargs, + ) + return model_inputs + + +__all__ = [ + "Phi4MultimodalAudioPreTrainedModel", + "Phi4MultimodalAudioModel", + "Phi4MultimodalVisionPreTrainedModel", + "Phi4MultimodalVisionModel", + "Phi4MultimodalPreTrainedModel", + "Phi4MultimodalModel", + "Phi4MultimodalForCausalLM", + "Phi4MultimodalVisionConfig", + "Phi4MultimodalAudioConfig", + "Phi4MultimodalConfig", +] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/phi4_multimodal/processing_phi4_multimodal.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/phi4_multimodal/processing_phi4_multimodal.py new file mode 100644 index 0000000000000000000000000000000000000000..325b27ed361c9234cebbebabb02068cce4e32e67 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/phi4_multimodal/processing_phi4_multimodal.py @@ -0,0 +1,133 @@ +# Copyright 2025 Microsoft and the HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +""" +Processor class for Phi4Multimodal +""" + +import re + +from ...audio_utils import AudioInput +from ...image_processing_utils import BatchFeature +from ...image_utils import ImageInput +from ...processing_utils import ProcessingKwargs, ProcessorMixin, Unpack +from ...tokenization_utils_base import TextInput +from ...utils import auto_docstring, logging + + +logger = logging.get_logger(__name__) + + +class Phi4MultimodalProcessorKwargs(ProcessingKwargs, total=False): + _defaults = { + "audio_kwargs": { + "device": "cpu", + }, + } + + +@auto_docstring +class Phi4MultimodalProcessor(ProcessorMixin): + def __init__( + self, + image_processor, + audio_processor, + tokenizer, + **kwargs, + ): + self.image_token = tokenizer.image_token + self.image_token_id = tokenizer.image_token_id + self.audio_token = tokenizer.audio_token + self.audio_token_id = tokenizer.audio_token_id + super().__init__(image_processor, audio_processor, tokenizer, **kwargs) + + @auto_docstring + def __call__( + self, + text: TextInput | list[TextInput], + images: ImageInput | None = None, + audio: AudioInput | None = None, + **kwargs: Unpack[Phi4MultimodalProcessorKwargs], + ) -> BatchFeature: + r""" + Returns: + [`BatchFeature`]: A [`BatchFeature`] with the following fields: + + - **input_ids** -- List of token ids to be fed to a model. + - **attention_mask** -- List of indices specifying which tokens should be attended to by the model. + - **input_image_embeds** -- Pixel values to be fed to a model. + - **image_sizes** -- List of tuples specifying the size of each image in `input_image_embeds`. + - **image_attention_mask** -- List of attention masks for each image in `input_image_embeds`. + - **input_audio_embeds** -- Audio embeddings to be fed to a model. + - **audio_embed_sizes** -- List of integers specifying the size of each audio in `input_audio_embeds`. + """ + + output_kwargs = self._merge_kwargs(Phi4MultimodalProcessorKwargs, self.tokenizer.init_kwargs, **kwargs) + image_kwargs = output_kwargs["images_kwargs"] + audio_kwargs = output_kwargs["audio_kwargs"] + + image_inputs = self.image_processor(images, **image_kwargs) if images is not None else {} + audio_inputs = self.audio_processor(audio, **audio_kwargs) if audio is not None else {} + + # We pop here for images as we don't need it later + num_img_tokens = image_inputs.pop("num_img_tokens", []) + audio_embed_sizes = audio_inputs.get("audio_embed_sizes", []) + + # Replace certain special tokens for compatibility + if isinstance(text, str): + text = [text] + elif not isinstance(text, list) and not isinstance(text[0], str): + raise TypeError("Invalid input text. Please provide a string, or a list of strings") + + image_token = self.tokenizer.image_token + audio_token = self.tokenizer.audio_token + + # Check that the number of special tokens is sound + concatenated_prompt = "".join(text) + if concatenated_prompt.count(image_token) != len(num_img_tokens): + raise ValueError( + "You should add as much image tokens `<|image|>` in your prompt as you pass `images` to the processor. ", + f"Input contains {concatenated_prompt.count(image_token)} tokens != {len(num_img_tokens)} images", + ) + if concatenated_prompt.count(audio_token) != len(audio_embed_sizes): + raise ValueError( + "You should add as much audio tokens `<|audio|>` in your prompt as you pass `audios` to the processor. " + f"Input contains {concatenated_prompt.count(audio_token)} tokens != {len(audio_embed_sizes)} audios" + ) + + # Add appropriate number of image/audio tokens (note that the count of replacement is dynamic) + image_count_iter = iter(num_img_tokens) + audio_count_iter = iter(audio_embed_sizes) + processed_text = [ + re.sub(re.escape(image_token), lambda _: image_token * next(image_count_iter), t) for t in text + ] + processed_text = [ + re.sub(re.escape(audio_token), lambda _: audio_token * next(audio_count_iter), t) for t in processed_text + ] + + return_tensors = output_kwargs["text_kwargs"].pop("return_tensors", None) + text_inputs = self.tokenizer(processed_text, **output_kwargs["text_kwargs"]) + self._check_special_mm_tokens(processed_text, text_inputs, modalities=["image"]) + + # prepare batch feature + data = { + **text_inputs, + **image_inputs, + **audio_inputs, + } + + return BatchFeature(data=data, tensor_type=return_tensors) + + +__all__ = ["Phi4MultimodalProcessor"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/phimoe/__init__.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/phimoe/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..e0849f5c5006e59ab19fee37230056d0add2744c --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/phimoe/__init__.py @@ -0,0 +1,28 @@ +# Copyright 2024 Microsoft and The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from typing import TYPE_CHECKING + +from ...utils import _LazyModule +from ...utils.import_utils import define_import_structure + + +if TYPE_CHECKING: + from .configuration_phimoe import * + from .modeling_phimoe import * + +else: + import sys + + _file = globals()["__file__"] + sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__) diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/phimoe/configuration_phimoe.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/phimoe/configuration_phimoe.py new file mode 100644 index 0000000000000000000000000000000000000000..512d6bddfb6a56084d774cf269d57af44dcc236d --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/phimoe/configuration_phimoe.py @@ -0,0 +1,198 @@ +# Copyright 2024 Microsoft and the HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +"""PyTorch Phi-MoE model.""" + +from ...configuration_utils import PreTrainedConfig +from ...modeling_rope_utils import RopeParameters +from ...utils import logging + + +logger = logging.get_logger(__name__) + + +class PhimoeConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`PhimoeModel`]. It is used to instantiate a Phi-moe + model according to the specified arguments, defining the model architecture. Instantiating a configuration with the + defaults will yield a similar configuration to that of the + [microsoft/Phi-3.5-MoE-instruct](https://huggingface.co/microsoft/Phi-3.5-MoE-instruct). + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + Args: + vocab_size (`int`, *optional*, defaults to 32064): + Vocabulary size of the Phimoe model. Defines the number of different tokens that can be represented by the + `inputs_ids` passed when calling [`PhimoeModel`] + hidden_size (`int`, *optional*, defaults to 4096): + Dimension of the hidden representations. + intermediate_size (`int`, *optional*, defaults to 6400): + Dimension of the MLP representations. + num_hidden_layers (`int`, *optional*, defaults to 32): + Number of hidden layers in the Transformer encoder. + num_attention_heads (`int`, *optional*, defaults to 32): + Number of attention heads for each attention layer in the Transformer encoder. + num_key_value_heads (`int`, *optional*, defaults to 8): + This is the number of key_value heads that should be used to implement Grouped Query Attention. If + `num_key_value_heads=num_attention_heads`, the model will use Multi Head Attention (MHA), if + `num_key_value_heads=1` the model will use Multi Query Attention (MQA) otherwise GQA is used. When + converting a multi-head checkpoint to a GQA checkpoint, each group key and value head should be constructed + by meanpooling all the original heads within that group. For more details, check out [this + paper](https://huggingface.co/papers/2305.13245). If it is not specified, will default to `8`. + hidden_act (`str` or `function`, *optional*, defaults to `"silu"`): + The non-linear activation function (function or string) in the decoder. + max_position_embeddings (`int`, *optional*, defaults to `4096*32`): + The maximum sequence length that this model might ever be used with. Mixtral's sliding window attention + allows sequence of up to 4096*32 tokens. + initializer_range (`float`, *optional*, defaults to 0.02): + The standard deviation of the truncated_normal_initializer for initializing all weight matrices. + rms_norm_eps (`float`, *optional*, defaults to 1e-05): + The epsilon used by the rms normalization layers. + use_cache (`bool`, *optional*, defaults to `True`): + Whether or not the model should return the last key/values attentions (not used by all models). Only + relevant if `config.is_decoder=True`. + pad_token_id (`int`, *optional*): + The id of the padding token. + bos_token_id (`int`, *optional*, defaults to 1): + The id of the "beginning-of-sequence" token. + eos_token_id (`int`, *optional*, defaults to 2): + The id of the "end-of-sequence" token. + tie_word_embeddings (`bool`, *optional*, defaults to `False`): + Whether the model's input and output word embeddings should be tied. + rope_parameters (`RopeParameters`, *optional*): + Dictionary containing the configuration parameters for the RoPE embeddings. The dictionary should contain + a value for `rope_theta` and optionally parameters used for scaling in case you want to use RoPE + with longer `max_position_embeddings`. + sliding_window (`int`, *optional*): + Sliding window attention window size. If not specified, will default to `262144`. + attention_dropout (`float`, *optional*, defaults to 0.0): + The dropout ratio for the attention probabilities. + num_experts_per_tok (`int`, *optional*, defaults to 2): + The number of experts to root per-token, can be also interpreted as the `top-p` routing + parameter + num_local_experts (`int`, *optional*, defaults to 16): + Number of experts per Sparse MLP layer. + output_router_logits (`bool`, *optional*, defaults to `False`): + Whether or not the router logits should be returned by the model. Enabling this will also + allow the model to output the auxiliary loss. See [here]() for more details + router_aux_loss_coef (`float`, *optional*, defaults to 0.001): + The aux loss factor for the total loss. + router_jitter_noise (`float`, *optional*, defaults to 0.01): + Amount of noise to add to the router. + input_jitter_noise (`float`, *optional*, defaults to 0.0): Input jitter noise + attention_bias (`bool`, *optional*, defaults to `False`): Attention bias + lm_head_bias (`bool`, *optional*, defaults to `False`): LM head bias + + Example: + + ```python + >>> from transformers import PhimoeModel, PhimoeConfig + >>> # Initializing a Phi-3 style configuration + >>> configuration = PhimoeConfig.from_pretrained("microsoft/Phi-3.5-MoE-instruct") + >>> # Initializing a model from the configuration + >>> model = PhimoeModel(configuration) + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "phimoe" + keys_to_ignore_at_inference = ["past_key_values"] + default_theta = 1000000.0 + + def __init__( + self, + vocab_size: int | None = 32064, + hidden_size: int | None = 4096, + intermediate_size: int | None = 6400, + num_hidden_layers: int | None = 32, + num_attention_heads: int | None = 32, + num_key_value_heads: int | None = 8, + hidden_act: str | None = "silu", + max_position_embeddings: int | None = 4096 * 32, + initializer_range: float | None = 0.02, + rms_norm_eps: int | None = 1e-5, + use_cache: bool | None = True, + pad_token_id: int | None = None, + bos_token_id: int | None = 1, + eos_token_id: int | None = 2, + tie_word_embeddings: int | None = False, + rope_parameters: RopeParameters | dict[str, RopeParameters] | None = None, + sliding_window: int | None = None, + attention_dropout: float | None = 0.0, + num_experts_per_tok: int | None = 2, + num_local_experts: int | None = 16, + output_router_logits: bool | None = False, + router_aux_loss_coef: float | None = 0.001, + router_jitter_noise: float | None = 0.01, + input_jitter_noise: float | None = 0.0, + attention_bias: bool | None = False, + lm_head_bias: bool | None = False, + **kwargs, + ): + self.vocab_size = vocab_size + self.max_position_embeddings = max_position_embeddings + self.hidden_size = hidden_size + self.intermediate_size = intermediate_size + self.num_hidden_layers = num_hidden_layers + self.num_attention_heads = num_attention_heads + self.sliding_window = sliding_window + self.attention_bias = attention_bias + self.lm_head_bias = lm_head_bias + # for backward compatibility + if num_key_value_heads is None: + num_key_value_heads = num_attention_heads + + self.num_key_value_heads = num_key_value_heads + self.hidden_act = hidden_act + self.initializer_range = initializer_range + self.rms_norm_eps = rms_norm_eps + self.use_cache = use_cache + self.attention_dropout = attention_dropout + + self.num_experts_per_tok = num_experts_per_tok + self.num_local_experts = num_local_experts + self.output_router_logits = output_router_logits + self.router_aux_loss_coef = router_aux_loss_coef + self.router_jitter_noise = router_jitter_noise + self.input_jitter_noise = input_jitter_noise + self.rope_parameters = rope_parameters + + self.tie_word_embeddings = tie_word_embeddings + self.pad_token_id = pad_token_id + self.bos_token_id = bos_token_id + self.eos_token_id = eos_token_id + super().__init__(**kwargs) + + def validate_rope(self, ignore_keys=None): + """ + Validate the `rope_parameters` configuration. + """ + super().validate_rope(ignore_keys=ignore_keys) + + # Run model-specific rope validation + if self.rope_parameters["rope_type"] != "default": + if "original_max_position_embeddings" in self.rope_parameters: + self.original_max_position_embeddings = self.rope_parameters["original_max_position_embeddings"] + rope_parameters_short_mscale = self.rope_parameters.get("short_mscale", None) + rope_parameters_long_mscale = self.rope_parameters.get("long_mscale", None) + if not isinstance(rope_parameters_short_mscale, (int, float)): + raise TypeError( + f"`rope_parameters`'s short_mscale field must be a number, got {rope_parameters_short_mscale}" + ) + if not isinstance(rope_parameters_long_mscale, (int, float)): + raise TypeError( + f"`rope_parameters`'s long_mscale field must be a number, got {rope_parameters_long_mscale}" + ) + + +__all__ = ["PhimoeConfig"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/phimoe/modeling_phimoe.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/phimoe/modeling_phimoe.py new file mode 100644 index 0000000000000000000000000000000000000000..8d88f3b041c50fedd780a2ff49c9353f7b0de2ea --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/phimoe/modeling_phimoe.py @@ -0,0 +1,931 @@ +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# This file was automatically generated from src/transformers/models/phimoe/modular_phimoe.py. +# Do NOT edit this file manually as any edits will be overwritten by the generation of +# the file from the modular. If any change should be done, please apply the change to the +# modular_phimoe.py file directly. One of our CI enforces this. +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# Copyright 2024 Microsoft and the HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + + +from collections.abc import Callable +from typing import Optional + +import torch +from torch import nn + +from ... import initialization as init +from ...activations import ACT2FN +from ...cache_utils import Cache, DynamicCache +from ...generation import GenerationMixin +from ...integrations import use_experts_implementation, use_kernel_func_from_hub, use_kernelized_func +from ...masking_utils import create_causal_mask, create_sliding_window_causal_mask +from ...modeling_layers import GenericForSequenceClassification, GradientCheckpointingLayer +from ...modeling_outputs import MoeCausalLMOutputWithPast, MoeModelOutputWithPast +from ...modeling_rope_utils import ROPE_INIT_FUNCTIONS, dynamic_rope_update +from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel +from ...processing_utils import Unpack +from ...utils import TransformersKwargs, auto_docstring, can_return_tuple +from ...utils.generic import maybe_autocast, merge_with_config_defaults +from ...utils.output_capturing import OutputRecorder, capture_outputs +from .configuration_phimoe import PhimoeConfig + + +class PhimoeRotaryEmbedding(nn.Module): + inv_freq: torch.Tensor # fix linting for `register_buffer` + + def __init__(self, config: PhimoeConfig, device=None): + super().__init__() + self.max_seq_len_cached = config.max_position_embeddings + self.original_max_seq_len = config.max_position_embeddings + + self.config = config + + self.rope_type = self.config.rope_parameters["rope_type"] + self.rope_init_fn: Callable = self.compute_default_rope_parameters + if self.rope_type != "default": + self.rope_init_fn = ROPE_INIT_FUNCTIONS[self.rope_type] + inv_freq, self.attention_scaling = self.rope_init_fn(self.config, device) + + self.register_buffer("inv_freq", inv_freq, persistent=False) + self.register_buffer("original_inv_freq", inv_freq.clone(), persistent=False) + + @staticmethod + def compute_default_rope_parameters( + config: PhimoeConfig | None = None, + device: Optional["torch.device"] = None, + seq_len: int | None = None, + ) -> tuple["torch.Tensor", float]: + """ + Computes the inverse frequencies according to the original RoPE implementation + Args: + config ([`~transformers.PreTrainedConfig`]): + The model configuration. + device (`torch.device`): + The device to use for initialization of the inverse frequencies. + seq_len (`int`, *optional*): + The current sequence length. Unused for this type of RoPE. + Returns: + Tuple of (`torch.Tensor`, `float`), containing the inverse frequencies for the RoPE embeddings and the + post-processing scaling factor applied to the computed cos/sin (unused in this type of RoPE). + """ + base = config.rope_parameters["rope_theta"] + dim = getattr(config, "head_dim", None) or config.hidden_size // config.num_attention_heads + + attention_factor = 1.0 # Unused in this type of RoPE + + # Compute the inverse frequencies + inv_freq = 1.0 / ( + base ** (torch.arange(0, dim, 2, dtype=torch.int64).to(device=device, dtype=torch.float) / dim) + ) + return inv_freq, attention_factor + + @torch.no_grad() + @dynamic_rope_update # power user: used with advanced RoPE types (e.g. dynamic rope) + def forward(self, x, position_ids=None, layer_type=None): + if layer_type is not None: + raise ValueError( + f"{self.__class__.__name__} does not support layer types, but got `layer_type={layer_type}`" + ) + + mscale = None + seq_len = torch.max(position_ids) + 1 + if self.config.rope_parameters["rope_type"] != "default" and seq_len: + mscale = ( + self.config.rope_parameters["long_mscale"] + if seq_len > self.config.rope_parameters["original_max_position_embeddings"] + else self.config.rope_parameters["short_mscale"] + ) + inv_freq, attention_scaling = self.rope_init_fn(self.config, x.device, seq_len) + mscale = attention_scaling if mscale is None else mscale + inv_freq_expanded = inv_freq[None, :, None].float().expand(position_ids.shape[0], -1, 1).to(x.device) + position_ids_expanded = position_ids[:, None, :].float() + + device_type = x.device.type if isinstance(x.device.type, str) and x.device.type != "mps" else "cpu" + with maybe_autocast(device_type=device_type, enabled=False): # Force float32 + freqs = (inv_freq_expanded.float() @ position_ids_expanded.float()).transpose(1, 2) + emb = torch.cat((freqs, freqs), dim=-1) + cos = emb.cos() * mscale + sin = emb.sin() * mscale + return cos.to(x.dtype), sin.to(x.dtype) + + +def rotate_half(x): + """Rotates half the hidden dims of the input.""" + x1 = x[..., : x.shape[-1] // 2] + x2 = x[..., x.shape[-1] // 2 :] + return torch.cat((-x2, x1), dim=-1) + + +@use_kernel_func_from_hub("rotary_pos_emb") +def apply_rotary_pos_emb(q, k, cos, sin, unsqueeze_dim=1): + """Applies Rotary Position Embedding to the query and key tensors. + + Args: + q (`torch.Tensor`): The query tensor. + k (`torch.Tensor`): The key tensor. + cos (`torch.Tensor`): The cosine part of the rotary embedding. + sin (`torch.Tensor`): The sine part of the rotary embedding. + unsqueeze_dim (`int`, *optional*, defaults to 1): + The 'unsqueeze_dim' argument specifies the dimension along which to unsqueeze cos[position_ids] and + sin[position_ids] so that they can be properly broadcasted to the dimensions of q and k. For example, note + that cos[position_ids] and sin[position_ids] have the shape [batch_size, seq_len, head_dim]. Then, if q and + k have the shape [batch_size, heads, seq_len, head_dim], then setting unsqueeze_dim=1 makes + cos[position_ids] and sin[position_ids] broadcastable to the shapes of q and k. Similarly, if q and k have + the shape [batch_size, seq_len, heads, head_dim], then set unsqueeze_dim=2. + Returns: + `tuple(torch.Tensor)` comprising of the query and key tensors rotated using the Rotary Position Embedding. + """ + cos = cos.unsqueeze(unsqueeze_dim) + sin = sin.unsqueeze(unsqueeze_dim) + q_embed = (q * cos) + (rotate_half(q) * sin) + k_embed = (k * cos) + (rotate_half(k) * sin) + return q_embed, k_embed + + +def repeat_kv(hidden_states: torch.Tensor, n_rep: int) -> torch.Tensor: + """ + This is the equivalent of torch.repeat_interleave(x, dim=1, repeats=n_rep). The hidden states go from (batch, + num_key_value_heads, seqlen, head_dim) to (batch, num_attention_heads, seqlen, head_dim) + """ + batch, num_key_value_heads, slen, head_dim = hidden_states.shape + if n_rep == 1: + return hidden_states + hidden_states = hidden_states[:, :, None, :, :].expand(batch, num_key_value_heads, n_rep, slen, head_dim) + return hidden_states.reshape(batch, num_key_value_heads * n_rep, slen, head_dim) + + +def eager_attention_forward( + module: nn.Module, + query: torch.Tensor, + key: torch.Tensor, + value: torch.Tensor, + attention_mask: torch.Tensor | None, + scaling: float, + dropout: float = 0.0, + **kwargs: Unpack[TransformersKwargs], +): + key_states = repeat_kv(key, module.num_key_value_groups) + value_states = repeat_kv(value, module.num_key_value_groups) + + attn_weights = torch.matmul(query, key_states.transpose(2, 3)) * scaling + if attention_mask is not None: + attn_weights = attn_weights + attention_mask + + attn_weights = nn.functional.softmax(attn_weights, dim=-1, dtype=torch.float32).to(query.dtype) + attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training) + attn_output = torch.matmul(attn_weights, value_states) + attn_output = attn_output.transpose(1, 2).contiguous() + + return attn_output, attn_weights + + +@use_kernelized_func(apply_rotary_pos_emb) +class PhimoeAttention(nn.Module): + """Multi-headed attention from 'Attention Is All You Need' paper""" + + def __init__(self, config: PhimoeConfig, layer_idx: int): + super().__init__() + self.config = config + self.layer_idx = layer_idx + self.head_dim = getattr(config, "head_dim", config.hidden_size // config.num_attention_heads) + self.num_key_value_groups = config.num_attention_heads // config.num_key_value_heads + self.scaling = self.head_dim**-0.5 + self.attention_dropout = config.attention_dropout + self.is_causal = True + + self.q_proj = nn.Linear( + config.hidden_size, config.num_attention_heads * self.head_dim, bias=config.attention_bias + ) + self.k_proj = nn.Linear( + config.hidden_size, config.num_key_value_heads * self.head_dim, bias=config.attention_bias + ) + self.v_proj = nn.Linear( + config.hidden_size, config.num_key_value_heads * self.head_dim, bias=config.attention_bias + ) + self.o_proj = nn.Linear( + config.num_attention_heads * self.head_dim, config.hidden_size, bias=config.attention_bias + ) + + def forward( + self, + hidden_states: torch.Tensor, + position_embeddings: tuple[torch.Tensor, torch.Tensor] | None = None, + attention_mask: torch.Tensor | None = None, + past_key_values: Cache | None = None, + cache_position: torch.LongTensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor, torch.Tensor]: + input_shape = hidden_states.shape[:-1] + hidden_shape = (*input_shape, -1, self.head_dim) + + query_states = self.q_proj(hidden_states).view(hidden_shape).transpose(1, 2) + key_states = self.k_proj(hidden_states).view(hidden_shape).transpose(1, 2) + value_states = self.v_proj(hidden_states).view(hidden_shape).transpose(1, 2) + + cos, sin = position_embeddings + query_states, key_states = apply_rotary_pos_emb(query_states, key_states, cos, sin) + + if past_key_values is not None: + # sin and cos are specific to RoPE models; cache_position needed for the static cache + cache_kwargs = {"sin": sin, "cos": cos, "cache_position": cache_position} + key_states, value_states = past_key_values.update(key_states, value_states, self.layer_idx, cache_kwargs) + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, eager_attention_forward + ) + + attn_output, attn_weights = attention_interface( + self, + query_states, + key_states, + value_states, + attention_mask, + dropout=0.0 if not self.training else self.attention_dropout, + scaling=self.scaling, + **kwargs, + ) + + attn_output = attn_output.reshape(*input_shape, -1).contiguous() + attn_output = self.o_proj(attn_output) + return attn_output, attn_weights + + +class PhimoeMultiplier(torch.autograd.Function): + @staticmethod + def forward( + ctx, + scores: torch.Tensor, + multiplier: torch.Tensor, + selected_experts: torch.Tensor, + masked_gates: torch.Tensor, + mask_for_one: torch.Tensor, + ): + """ + Forward pass for the custom autograd function. + + Args: + ctx: Context object to save information for backward computation. + scores (torch.Tensor): Input scores tensor. + multiplier (torch.Tensor): Multiplier tensor. + selected_experts (torch.Tensor): Tensor of selected experts. + masked_gates (torch.Tensor): Masked gates tensor. + mask_for_one (torch.Tensor): Mask for one tensor. + + Returns: + torch.Tensor: Result of the forward pass. + """ + ctx.save_for_backward(multiplier, selected_experts, masked_gates) + return multiplier * mask_for_one + + @staticmethod + def backward( + ctx, + grad_at_output: torch.Tensor, + ): + """ + Backward pass for the custom autograd function. + + Args: + ctx: Context object with saved tensors from the forward pass. + grad_at_output (torch.Tensor): Gradient at the output. + + Returns: + tuple[torch.Tensor, None, None, None, None]: Gradients for the inputs. + """ + multiplier, selected_experts, masked_gates = ctx.saved_tensors + + grad_at_output = grad_at_output * multiplier + + grad_at_scores_expanded = masked_gates * grad_at_output.mul(-1) + grad_at_scores_expanded.scatter_add_( + dim=-1, + index=selected_experts, + src=grad_at_output, + ) + + return ( + grad_at_scores_expanded, + None, + None, + None, + None, + ) + + +@use_experts_implementation +class PhimoeExperts(nn.Module): + """Collection of expert weights stored as 3D tensors.""" + + def __init__(self, config: PhimoeConfig): + super().__init__() + self.num_experts = config.num_local_experts + self.hidden_dim = config.hidden_size + self.intermediate_dim = config.intermediate_size + self.gate_up_proj = nn.Parameter(torch.empty(self.num_experts, 2 * self.intermediate_dim, self.hidden_dim)) + self.down_proj = nn.Parameter(torch.empty(self.num_experts, self.hidden_dim, self.intermediate_dim)) + self.act_fn = ACT2FN[config.hidden_act] + + def forward( + self, + hidden_states: torch.Tensor, + top_k_index: torch.Tensor, + top_k_weights: torch.Tensor, + ) -> torch.Tensor: + final_hidden_states = torch.zeros_like(hidden_states) + with torch.no_grad(): + expert_mask = torch.nn.functional.one_hot(top_k_index, num_classes=self.num_experts) + expert_mask = expert_mask.permute(2, 1, 0) + expert_hit = torch.greater(expert_mask.sum(dim=(-1, -2)), 0).nonzero() + + for expert_idx in expert_hit: + expert_idx = expert_idx[0] + if expert_idx == self.num_experts: + continue + top_k_pos, token_idx = torch.where(expert_mask[expert_idx]) + current_state = hidden_states[token_idx] + gate, up = nn.functional.linear(current_state, self.gate_up_proj[expert_idx]).chunk(2, dim=-1) + current_hidden_states = self.act_fn(gate) * up + current_hidden_states = nn.functional.linear(current_hidden_states, self.down_proj[expert_idx]) + current_hidden_states = current_hidden_states * top_k_weights[token_idx, top_k_pos, None] + final_hidden_states.index_add_(0, token_idx, current_hidden_states.to(final_hidden_states.dtype)) + + return final_hidden_states + + +def sparsemixer(scores, jitter_eps, training, top_k=2): + """ + Sparse mixer function to select top-k experts and compute multipliers. + Based on the paper: https://huggingface.co/papers/2409.12136 + We first replace the TopK(·) function as random sampling of discrete variables + in model training. Then, following Liu et al. (2023a) and Liu et al. (2023b), we apply Heun's + third order method to approximate the expert routing gradient and construct a modified + back-propagation to give a mathematically sound gradient estimation for expert routing. + + Args: + scores (torch.Tensor): Input scores tensor. + jitter_eps (float): Jitter epsilon for numerical stability. + training (bool): Flag indicating if the model is in training mode. + top_k (int): Number of top experts to select. + + Returns: + tuple[torch.Tensor, torch.Tensor]: Multiplier and selected experts tensors. + """ + with torch.no_grad(): + # Compute mask for sparsity + mask_logits_threshold, max_ind = scores.max(dim=-1, keepdim=True) + factor = scores.abs().clamp(min=mask_logits_threshold) + mask_logits_threshold = ((mask_logits_threshold - scores) / factor) > (2 * jitter_eps) + + # Apply mask + masked_gates = scores.masked_fill(mask_logits_threshold, float("-inf")) + if training: + selected_experts = ( + ( + masked_gates + - torch.empty_like(masked_gates, memory_format=torch.legacy_contiguous_format).exponential_().log() + ) + .max(dim=-1)[1] + .unsqueeze(-1) + ) # Gumbel sampling, more robust than the multinomial method + else: + selected_experts = max_ind + + # Compute scores for gradients + masked_gates = torch.softmax(masked_gates, dim=-1) + multiplier_o = masked_gates.gather(dim=-1, index=selected_experts) + + if training: + # Compute midpoint mask + max_scores, max_ind = masked_gates.max(dim=-1, keepdim=True) + mask_for_one = torch.logical_or( + selected_experts == max_ind, + torch.rand_like(max_scores) > 0.75, # Heun's third-order method + ) + # 1 -> 1.0 & 0 -> 1./3: lambda x: (x + 0.5) / 1.5 + mask_for_one = torch.add(0.3333, mask_for_one, alpha=0.6667).type_as(masked_gates) + + multiplier = PhimoeMultiplier.apply( + scores, + multiplier_o, + selected_experts, + masked_gates, + mask_for_one, + ) + else: + multiplier = multiplier_o + + # Masked out first expert + masked_scores = torch.scatter( + scores, + -1, + selected_experts, + float("-inf"), + ) + with torch.no_grad(): + # Compute mask for sparsity + mask_logits_threshold, max_ind = masked_scores.max(dim=-1, keepdim=True) + factor = scores.abs().clamp(min=mask_logits_threshold) + mask_logits_threshold = ((mask_logits_threshold - scores) / factor) > (2 * jitter_eps) + + # Apply mask + masked_gates_top2 = masked_scores.masked_fill(mask_logits_threshold, float("-inf")) + if training: + selected_experts_top2 = ( + ( + masked_gates_top2 + - torch.empty_like(masked_gates_top2, memory_format=torch.legacy_contiguous_format) + .exponential_() + .log() + ) + .max(dim=-1)[1] + .unsqueeze(-1) + ) # Gumbel sampling, more robust than the multinomial method + else: + selected_experts_top2 = max_ind + # Compute scores for gradients + masked_gates_top2 = torch.softmax(masked_gates_top2, dim=-1) + multiplier_top2_o = masked_gates_top2.gather(dim=-1, index=selected_experts_top2) + + if training: + # Compute midpoint mask + max_scores, max_ind = masked_gates_top2.max(dim=-1, keepdim=True) + mask_for_one_top2 = torch.logical_or( + selected_experts_top2 == max_ind, + torch.rand_like(max_scores).uniform_() > 0.75, # Heun's third-order method + ) + # 1 -> 1.0 & 0 -> 1./3: lambda x: (x + 0.5) / 1.5 + mask_for_one_top2 = torch.add(0.3333, mask_for_one_top2, alpha=0.6667).type_as(masked_gates_top2) + + multiplier_top2 = PhimoeMultiplier.apply( + scores, + multiplier_top2_o, + selected_experts_top2, + masked_gates_top2, + mask_for_one_top2, + ) + else: + multiplier_top2 = multiplier_top2_o + + multiplier = torch.concat((multiplier, multiplier_top2), dim=-1) + selected_experts = torch.concat((selected_experts, selected_experts_top2), dim=-1) + + return ( + multiplier, + selected_experts, + ) + + +class PhimoeTopKRouter(nn.Linear): + def __init__(self, config: PhimoeConfig): + super().__init__(config.hidden_size, config.num_local_experts, bias=False) + self.router_jitter_noise = config.router_jitter_noise + self.input_jitter_noise = config.input_jitter_noise + self.top_k = config.num_experts_per_tok + + def forward(self, hidden_states: torch.Tensor) -> tuple[torch.Tensor, torch.Tensor]: + if self.training and self.input_jitter_noise > 0: + hidden_states *= torch.empty_like(hidden_states).uniform_( + 1.0 - self.input_jitter_noise, 1.0 + self.input_jitter_noise + ) + router_logits = super().forward(hidden_states) + routing_weights, selected_experts = sparsemixer( + router_logits, jitter_eps=self.router_jitter_noise, training=self.training, top_k=self.top_k + ) + return router_logits, routing_weights, selected_experts + + +class PhimoeSparseMoeBlock(nn.Module): + """ + This implementation is + strictly equivalent to standard MoE with full capacity (no + dropped tokens). It's faster since it formulates MoE operations + in terms of block-sparse operations to accommodate imbalanced + assignments of tokens to experts, whereas standard MoE either + (1) drop tokens at the cost of reduced performance or (2) set + capacity factor to number of experts and thus waste computation + and memory on padding. + """ + + def __init__(self, config): + super().__init__() + self.hidden_dim = config.hidden_size + self.ffn_dim = config.intermediate_size + self.num_experts = config.num_local_experts + self.top_k = config.num_experts_per_tok + self.router = PhimoeTopKRouter(config) + self.experts = PhimoeExperts(config) + self.input_jitter_noise = config.input_jitter_noise + + def forward(self, hidden_states: torch.Tensor) -> torch.Tensor: + batch_size, sequence_length, hidden_dim = hidden_states.shape + if self.training and self.input_jitter_noise > 0: + hidden_states *= torch.empty_like(hidden_states).uniform_( + 1.0 - self.input_jitter_noise, 1.0 + self.input_jitter_noise + ) + + batch_size, sequence_length, hidden_dim = hidden_states.shape + hidden_states = hidden_states.reshape(-1, hidden_dim) + _, routing_weights, selected_experts = self.router(hidden_states) + final_hidden_states = self.experts(hidden_states, selected_experts, routing_weights) + return final_hidden_states.reshape(batch_size, sequence_length, hidden_dim) + + +class PhimoeDecoderLayer(GradientCheckpointingLayer): + def __init__(self, config: PhimoeConfig, layer_idx: int): + super().__init__() + self.hidden_size = config.hidden_size + + self.self_attn = PhimoeAttention(config, layer_idx) + + self.mlp = PhimoeSparseMoeBlock(config) + + # Phimoe uses nn.LayerNorm + self.input_layernorm = nn.LayerNorm(config.hidden_size, eps=config.rms_norm_eps, elementwise_affine=True) + self.post_attention_layernorm = nn.LayerNorm( + config.hidden_size, eps=config.rms_norm_eps, elementwise_affine=True + ) + + def forward( + self, + hidden_states: torch.Tensor, + position_embeddings: tuple[torch.Tensor, torch.Tensor] | None = None, + attention_mask: torch.Tensor | None = None, + position_ids: torch.LongTensor | None = None, + past_key_values: Cache | None = None, + cache_position: torch.LongTensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> torch.Tensor: + residual = hidden_states + hidden_states = self.input_layernorm(hidden_states) + hidden_states, _ = self.self_attn( + hidden_states=hidden_states, + position_embeddings=position_embeddings, + attention_mask=attention_mask, + position_ids=position_ids, + past_key_values=past_key_values, + cache_position=cache_position, + **kwargs, + ) + hidden_states = residual + hidden_states + residual = hidden_states + hidden_states = self.post_attention_layernorm(hidden_states) + hidden_states = self.mlp(hidden_states) + hidden_states = residual + hidden_states + return hidden_states + + +@auto_docstring +class PhimoePreTrainedModel(PreTrainedModel): + config: PhimoeConfig + base_model_prefix = "model" + supports_gradient_checkpointing = True + _no_split_modules = ["PhimoeDecoderLayer"] + _skip_keys_device_placement = ["past_key_values"] + _supports_flash_attn = True + _supports_sdpa = True + _supports_flex_attn = True + + _can_compile_fullgraph = True + _supports_attention_backend = True + _can_record_outputs = { + "router_logits": OutputRecorder(PhimoeTopKRouter, index=0), + "hidden_states": PhimoeDecoderLayer, + "attentions": PhimoeAttention, + } + + @torch.no_grad() + def _init_weights(self, module): + super()._init_weights(module) + std = self.config.initializer_range + if isinstance(module, PhimoeExperts): + init.normal_(module.gate_up_proj, mean=0.0, std=std) + init.normal_(module.down_proj, mean=0.0, std=std) + elif isinstance(module, PhimoeTopKRouter): + init.normal_(module.weight, mean=0.0, std=std) + + +@auto_docstring +class PhimoeModel(PhimoePreTrainedModel): + def __init__(self, config: PhimoeConfig): + super().__init__(config) + self.padding_idx = config.pad_token_id + self.vocab_size = config.vocab_size + + self.embed_tokens = nn.Embedding(config.vocab_size, config.hidden_size, self.padding_idx) + self.layers = nn.ModuleList( + [PhimoeDecoderLayer(config, layer_idx) for layer_idx in range(config.num_hidden_layers)] + ) + self.norm = nn.LayerNorm(config.hidden_size, eps=config.rms_norm_eps, elementwise_affine=True) + self.rotary_emb = PhimoeRotaryEmbedding(config=config) + self.gradient_checkpointing = False + + # Initialize weights and apply final processing + self.post_init() + + @merge_with_config_defaults + @capture_outputs + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.Tensor | None = None, + position_ids: torch.LongTensor | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.FloatTensor | None = None, + use_cache: bool | None = None, + cache_position: torch.LongTensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> MoeModelOutputWithPast: + if (input_ids is None) ^ (inputs_embeds is not None): + raise ValueError("You must specify exactly one of input_ids or inputs_embeds") + + if use_cache and past_key_values is None: + past_key_values = DynamicCache(config=self.config) + + if inputs_embeds is None: + inputs_embeds = self.embed_tokens(input_ids) + + if cache_position is None: + past_seen_tokens = past_key_values.get_seq_length() if past_key_values is not None else 0 + cache_position = torch.arange( + past_seen_tokens, past_seen_tokens + inputs_embeds.shape[1], device=inputs_embeds.device + ) + if position_ids is None: + position_ids = cache_position.unsqueeze(0) + + mask_function = create_causal_mask if self.config.sliding_window is None else create_sliding_window_causal_mask + causal_mask = mask_function( + config=self.config, + inputs_embeds=inputs_embeds, + attention_mask=attention_mask, + cache_position=cache_position, + past_key_values=past_key_values, + position_ids=position_ids, + ) + + hidden_states = inputs_embeds + position_embeddings = self.rotary_emb(hidden_states, position_ids=position_ids) + + for decoder_layer in self.layers[: self.config.num_hidden_layers]: + hidden_states = decoder_layer( + hidden_states, + attention_mask=causal_mask, + position_ids=position_ids, + past_key_values=past_key_values, + use_cache=use_cache, + cache_position=cache_position, + position_embeddings=position_embeddings, + **kwargs, + ) + + hidden_states = self.norm(hidden_states) + + return MoeModelOutputWithPast( # only diff with Mistral is the output type, we need MoE + last_hidden_state=hidden_states, + past_key_values=past_key_values, + ) + + +def load_balancing_loss_func( + gate_logits: torch.Tensor | tuple[torch.Tensor] | None, + num_experts: int | None = None, + top_k=2, + attention_mask: torch.Tensor | None = None, +) -> torch.Tensor | int: + r""" + Computes auxiliary load balancing loss as in Switch Transformer - implemented in Pytorch. + + See Switch Transformer (https://huggingface.co/papers/2101.03961) for more details. This function implements the loss + function presented in equations (4) - (6) of the paper. It aims at penalizing cases where the routing between + experts is too unbalanced. + + Args: + gate_logits: + Logits from the `gate`, should be a tuple of model.config.num_hidden_layers tensors of + shape [batch_size X sequence_length, num_experts]. + num_experts: + Number of experts + top_k: + The number of experts to route per-token, can be also interpreted as the `top-k` routing + parameter. + attention_mask (`torch.Tensor`, *optional*): + The attention_mask used in forward function + shape [batch_size X sequence_length] if not None. + + Returns: + The auxiliary loss. + """ + if gate_logits is None or not isinstance(gate_logits, tuple): + return 0 + + if isinstance(gate_logits, tuple): + compute_device = gate_logits[0].device + concatenated_gate_logits = torch.cat([layer_gate.to(compute_device) for layer_gate in gate_logits], dim=0) + + routing_weights = torch.nn.functional.softmax(concatenated_gate_logits, dim=-1) + + _, selected_experts = torch.topk(routing_weights, top_k, dim=-1) + + expert_mask = torch.nn.functional.one_hot(selected_experts, num_experts) + + if attention_mask is None: + # Compute the percentage of tokens routed to each experts + tokens_per_expert = torch.mean(expert_mask.float(), dim=0) + + # Compute the average probability of routing to these experts + router_prob_per_expert = torch.mean(routing_weights, dim=0) + else: + batch_size, sequence_length = attention_mask.shape + num_hidden_layers = concatenated_gate_logits.shape[0] // (batch_size * sequence_length) + + # Compute the mask that masks all padding tokens as 0 with the same shape of expert_mask + expert_attention_mask = ( + attention_mask[None, :, :, None, None] + .expand((num_hidden_layers, batch_size, sequence_length, top_k, num_experts)) + .reshape(-1, top_k, num_experts) + .to(compute_device) + ) + + # Compute the percentage of tokens routed to each experts + tokens_per_expert = torch.sum(expert_mask.float() * expert_attention_mask, dim=0) / torch.sum( + expert_attention_mask, dim=0 + ) + + # Compute the mask that masks all padding tokens as 0 with the same shape of tokens_per_expert + router_per_expert_attention_mask = ( + attention_mask[None, :, :, None] + .expand((num_hidden_layers, batch_size, sequence_length, num_experts)) + .reshape(-1, num_experts) + .to(compute_device) + ) + + # Compute the average probability of routing to these experts + router_prob_per_expert = torch.sum(routing_weights * router_per_expert_attention_mask, dim=0) / torch.sum( + router_per_expert_attention_mask, dim=0 + ) + + overall_loss = torch.sum(tokens_per_expert * router_prob_per_expert.unsqueeze(0)) + return overall_loss * num_experts + + +@auto_docstring +class PhimoeForCausalLM(PhimoePreTrainedModel, GenerationMixin): + _tied_weights_keys = {"lm_head.weight": "model.embed_tokens.weight"} + _tp_plan = {"lm_head": "colwise_gather_output"} + _pp_plan = {"lm_head": (["hidden_states"], ["logits"])} + + def __init__(self, config): + super().__init__(config) + self.model = PhimoeModel(config) + self.vocab_size = config.vocab_size + self.lm_head = nn.Linear(config.hidden_size, config.vocab_size, bias=self.config.lm_head_bias) + self.router_aux_loss_coef = config.router_aux_loss_coef + self.num_experts = config.num_local_experts + self.num_experts_per_tok = config.num_experts_per_tok + + # Initialize weights and apply final processing + self.post_init() + + @can_return_tuple + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.Tensor | None = None, + position_ids: torch.LongTensor | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.FloatTensor | None = None, + labels: torch.LongTensor | None = None, + use_cache: bool | None = None, + output_router_logits: bool | None = None, + cache_position: torch.LongTensor | None = None, + logits_to_keep: int | torch.Tensor = 0, + **kwargs: Unpack[TransformersKwargs], + ) -> MoeCausalLMOutputWithPast: + r""" + labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Labels for computing the masked language modeling loss. Indices should either be in `[0, ..., + config.vocab_size]` or -100 (see `input_ids` docstring). Tokens with indices set to `-100` are ignored + (masked), the loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]`. + + Example: + + ```python + >>> from transformers import AutoTokenizer, PhimoeForCausalLM + + >>> model = PhimoeForCausalLM.from_pretrained("mistralai/Phimoe-8x7B-v0.1") + >>> tokenizer = AutoTokenizer.from_pretrained("mistralai/Phimoe-8x7B-v0.1") + + >>> prompt = "Hey, are you conscious? Can you talk to me?" + >>> inputs = tokenizer(prompt, return_tensors="pt") + + >>> # Generate + >>> generate_ids = model.generate(inputs.input_ids, max_length=30) + >>> tokenizer.batch_decode(generate_ids, skip_special_tokens=True, clean_up_tokenization_spaces=False)[0] + "Hey, are you conscious? Can you talk to me?\nI'm not conscious, but I can talk to you." + ```""" + + output_router_logits = ( + output_router_logits if output_router_logits is not None else self.config.output_router_logits + ) + + # decoder outputs consists of (dec_features, layer_state, dec_hidden, dec_attn) + outputs: MoeModelOutputWithPast = self.model( + input_ids=input_ids, + attention_mask=attention_mask, + position_ids=position_ids, + past_key_values=past_key_values, + inputs_embeds=inputs_embeds, + use_cache=use_cache, + output_router_logits=output_router_logits, + cache_position=cache_position, + **kwargs, + ) + + hidden_states = outputs.last_hidden_state + # Only compute necessary logits, and do not upcast them to float if we are not computing the loss + slice_indices = slice(-logits_to_keep, None) if isinstance(logits_to_keep, int) else logits_to_keep + logits = self.lm_head(hidden_states[:, slice_indices, :]) + + loss = None + if labels is not None: + loss = self.loss_function(logits, labels, self.vocab_size, **kwargs) + + aux_loss = None + if output_router_logits: + aux_loss = load_balancing_loss_func( + outputs.router_logits, + self.num_experts, + self.num_experts_per_tok, + attention_mask, + ) + if labels is not None: + loss += self.router_aux_loss_coef * aux_loss.to(loss.device) # make sure to reside in the same device + + return MoeCausalLMOutputWithPast( + loss=loss, + aux_loss=aux_loss, + logits=logits, + past_key_values=outputs.past_key_values, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + router_logits=outputs.router_logits, + ) + + # Copied from transformers.models.phi3.modeling_phi3.Phi3ForCausalLM.prepare_inputs_for_generation + def prepare_inputs_for_generation( + self, + input_ids, + past_key_values=None, + attention_mask=None, + inputs_embeds=None, + cache_position=None, + position_ids=None, + use_cache=True, + logits_to_keep=None, + **kwargs, + ): + # Overwritten -- this model may need to switch between short and long rope, invalidating the cache in the + # process + + # When the first time input length reached long and short factor switching point, enforce re-compute cache + # It will cause downside of slower at this single token position, however, better than current failure. + if ( + past_key_values + and hasattr(self.config, "original_max_position_embeddings") + and input_ids.shape[1] >= self.config.original_max_position_embeddings + 1 + ): + past_length = cache_position[0] + if past_length <= self.config.original_max_position_embeddings: + past_key_values = None + + model_inputs = super().prepare_inputs_for_generation( + input_ids=input_ids, + past_key_values=past_key_values, + attention_mask=attention_mask, + inputs_embeds=inputs_embeds, + cache_position=cache_position, + position_ids=position_ids, + use_cache=use_cache, + logits_to_keep=logits_to_keep, + **kwargs, + ) + return model_inputs + + +class PhimoeForSequenceClassification(GenericForSequenceClassification, PhimoePreTrainedModel): ... + + +__all__ = ["PhimoePreTrainedModel", "PhimoeModel", "PhimoeForCausalLM", "PhimoeForSequenceClassification"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/phimoe/modular_phimoe.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/phimoe/modular_phimoe.py new file mode 100644 index 0000000000000000000000000000000000000000..b24aedf54c736118be35abe2eccdc7740dbf831e --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/phimoe/modular_phimoe.py @@ -0,0 +1,412 @@ +# Copyright 2024 Microsoft and the HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +"""PyTorch Phimoe model.""" + +from collections.abc import Callable + +import torch +from torch import nn + +from ...modeling_layers import ( + GenericForSequenceClassification, +) +from ...modeling_rope_utils import ROPE_INIT_FUNCTIONS +from ...utils.generic import maybe_autocast +from ...utils.output_capturing import OutputRecorder +from ..llama.modeling_llama import LlamaAttention +from ..mixtral.modeling_mixtral import ( + MixtralDecoderLayer, + MixtralExperts, + MixtralForCausalLM, + MixtralModel, + MixtralPreTrainedModel, + MixtralRotaryEmbedding, +) +from .configuration_phimoe import PhimoeConfig + + +class PhimoeRotaryEmbedding(MixtralRotaryEmbedding): + def __init__(self, config: PhimoeConfig, device=None): + nn.Module.__init__() + self.max_seq_len_cached = config.max_position_embeddings + self.original_max_seq_len = config.max_position_embeddings + + self.config = config + + self.rope_type = self.config.rope_parameters["rope_type"] + self.rope_init_fn: Callable = self.compute_default_rope_parameters + if self.rope_type != "default": + self.rope_init_fn = ROPE_INIT_FUNCTIONS[self.rope_type] + inv_freq, self.attention_scaling = self.rope_init_fn(self.config, device) + + self.register_buffer("inv_freq", inv_freq, persistent=False) + self.register_buffer("original_inv_freq", inv_freq.clone(), persistent=False) + + def forward(self, x, position_ids=None, layer_type=None): + if layer_type is not None: + raise ValueError( + f"{self.__class__.__name__} does not support layer types, but got `layer_type={layer_type}`" + ) + + mscale = None + seq_len = torch.max(position_ids) + 1 + if self.config.rope_parameters["rope_type"] != "default" and seq_len: + mscale = ( + self.config.rope_parameters["long_mscale"] + if seq_len > self.config.rope_parameters["original_max_position_embeddings"] + else self.config.rope_parameters["short_mscale"] + ) + inv_freq, attention_scaling = self.rope_init_fn(self.config, x.device, seq_len) + mscale = attention_scaling if mscale is None else mscale + inv_freq_expanded = inv_freq[None, :, None].float().expand(position_ids.shape[0], -1, 1).to(x.device) + position_ids_expanded = position_ids[:, None, :].float() + + device_type = x.device.type if isinstance(x.device.type, str) and x.device.type != "mps" else "cpu" + with maybe_autocast(device_type=device_type, enabled=False): # Force float32 + freqs = (inv_freq_expanded.float() @ position_ids_expanded.float()).transpose(1, 2) + emb = torch.cat((freqs, freqs), dim=-1) + cos = emb.cos() * mscale + sin = emb.sin() * mscale + return cos.to(x.dtype), sin.to(x.dtype) + + +class PhimoeAttention(LlamaAttention): + pass + + +class PhimoeMultiplier(torch.autograd.Function): + @staticmethod + def forward( + ctx, + scores: torch.Tensor, + multiplier: torch.Tensor, + selected_experts: torch.Tensor, + masked_gates: torch.Tensor, + mask_for_one: torch.Tensor, + ): + """ + Forward pass for the custom autograd function. + + Args: + ctx: Context object to save information for backward computation. + scores (torch.Tensor): Input scores tensor. + multiplier (torch.Tensor): Multiplier tensor. + selected_experts (torch.Tensor): Tensor of selected experts. + masked_gates (torch.Tensor): Masked gates tensor. + mask_for_one (torch.Tensor): Mask for one tensor. + + Returns: + torch.Tensor: Result of the forward pass. + """ + ctx.save_for_backward(multiplier, selected_experts, masked_gates) + return multiplier * mask_for_one + + @staticmethod + def backward( + ctx, + grad_at_output: torch.Tensor, + ): + """ + Backward pass for the custom autograd function. + + Args: + ctx: Context object with saved tensors from the forward pass. + grad_at_output (torch.Tensor): Gradient at the output. + + Returns: + tuple[torch.Tensor, None, None, None, None]: Gradients for the inputs. + """ + multiplier, selected_experts, masked_gates = ctx.saved_tensors + + grad_at_output = grad_at_output * multiplier + + grad_at_scores_expanded = masked_gates * grad_at_output.mul(-1) + grad_at_scores_expanded.scatter_add_( + dim=-1, + index=selected_experts, + src=grad_at_output, + ) + + return ( + grad_at_scores_expanded, + None, + None, + None, + None, + ) + + +def sparsemixer(scores, jitter_eps, training, top_k=2): + """ + Sparse mixer function to select top-k experts and compute multipliers. + Based on the paper: https://huggingface.co/papers/2409.12136 + We first replace the TopK(·) function as random sampling of discrete variables + in model training. Then, following Liu et al. (2023a) and Liu et al. (2023b), we apply Heun's + third order method to approximate the expert routing gradient and construct a modified + back-propagation to give a mathematically sound gradient estimation for expert routing. + + Args: + scores (torch.Tensor): Input scores tensor. + jitter_eps (float): Jitter epsilon for numerical stability. + training (bool): Flag indicating if the model is in training mode. + top_k (int): Number of top experts to select. + + Returns: + tuple[torch.Tensor, torch.Tensor]: Multiplier and selected experts tensors. + """ + with torch.no_grad(): + # Compute mask for sparsity + mask_logits_threshold, max_ind = scores.max(dim=-1, keepdim=True) + factor = scores.abs().clamp(min=mask_logits_threshold) + mask_logits_threshold = ((mask_logits_threshold - scores) / factor) > (2 * jitter_eps) + + # Apply mask + masked_gates = scores.masked_fill(mask_logits_threshold, float("-inf")) + if training: + selected_experts = ( + ( + masked_gates + - torch.empty_like(masked_gates, memory_format=torch.legacy_contiguous_format).exponential_().log() + ) + .max(dim=-1)[1] + .unsqueeze(-1) + ) # Gumbel sampling, more robust than the multinomial method + else: + selected_experts = max_ind + + # Compute scores for gradients + masked_gates = torch.softmax(masked_gates, dim=-1) + multiplier_o = masked_gates.gather(dim=-1, index=selected_experts) + + if training: + # Compute midpoint mask + max_scores, max_ind = masked_gates.max(dim=-1, keepdim=True) + mask_for_one = torch.logical_or( + selected_experts == max_ind, + torch.rand_like(max_scores) > 0.75, # Heun's third-order method + ) + # 1 -> 1.0 & 0 -> 1./3: lambda x: (x + 0.5) / 1.5 + mask_for_one = torch.add(0.3333, mask_for_one, alpha=0.6667).type_as(masked_gates) + + multiplier = PhimoeMultiplier.apply( + scores, + multiplier_o, + selected_experts, + masked_gates, + mask_for_one, + ) + else: + multiplier = multiplier_o + + # Masked out first expert + masked_scores = torch.scatter( + scores, + -1, + selected_experts, + float("-inf"), + ) + with torch.no_grad(): + # Compute mask for sparsity + mask_logits_threshold, max_ind = masked_scores.max(dim=-1, keepdim=True) + factor = scores.abs().clamp(min=mask_logits_threshold) + mask_logits_threshold = ((mask_logits_threshold - scores) / factor) > (2 * jitter_eps) + + # Apply mask + masked_gates_top2 = masked_scores.masked_fill(mask_logits_threshold, float("-inf")) + if training: + selected_experts_top2 = ( + ( + masked_gates_top2 + - torch.empty_like(masked_gates_top2, memory_format=torch.legacy_contiguous_format) + .exponential_() + .log() + ) + .max(dim=-1)[1] + .unsqueeze(-1) + ) # Gumbel sampling, more robust than the multinomial method + else: + selected_experts_top2 = max_ind + # Compute scores for gradients + masked_gates_top2 = torch.softmax(masked_gates_top2, dim=-1) + multiplier_top2_o = masked_gates_top2.gather(dim=-1, index=selected_experts_top2) + + if training: + # Compute midpoint mask + max_scores, max_ind = masked_gates_top2.max(dim=-1, keepdim=True) + mask_for_one_top2 = torch.logical_or( + selected_experts_top2 == max_ind, + torch.rand_like(max_scores).uniform_() > 0.75, # Heun's third-order method + ) + # 1 -> 1.0 & 0 -> 1./3: lambda x: (x + 0.5) / 1.5 + mask_for_one_top2 = torch.add(0.3333, mask_for_one_top2, alpha=0.6667).type_as(masked_gates_top2) + + multiplier_top2 = PhimoeMultiplier.apply( + scores, + multiplier_top2_o, + selected_experts_top2, + masked_gates_top2, + mask_for_one_top2, + ) + else: + multiplier_top2 = multiplier_top2_o + + multiplier = torch.concat((multiplier, multiplier_top2), dim=-1) + selected_experts = torch.concat((selected_experts, selected_experts_top2), dim=-1) + + return ( + multiplier, + selected_experts, + ) + + +class PhimoeExperts(MixtralExperts): + pass + + +class PhimoeTopKRouter(nn.Linear): + def __init__(self, config: PhimoeConfig): + super().__init__(config.hidden_size, config.num_local_experts, bias=False) + self.router_jitter_noise = config.router_jitter_noise + self.input_jitter_noise = config.input_jitter_noise + self.top_k = config.num_experts_per_tok + + def forward(self, hidden_states: torch.Tensor) -> tuple[torch.Tensor, torch.Tensor]: + if self.training and self.input_jitter_noise > 0: + hidden_states *= torch.empty_like(hidden_states).uniform_( + 1.0 - self.input_jitter_noise, 1.0 + self.input_jitter_noise + ) + router_logits = super().forward(hidden_states) + routing_weights, selected_experts = sparsemixer( + router_logits, jitter_eps=self.router_jitter_noise, training=self.training, top_k=self.top_k + ) + return router_logits, routing_weights, selected_experts + + +class PhimoeSparseMoeBlock(nn.Module): + """ + This implementation is + strictly equivalent to standard MoE with full capacity (no + dropped tokens). It's faster since it formulates MoE operations + in terms of block-sparse operations to accommodate imbalanced + assignments of tokens to experts, whereas standard MoE either + (1) drop tokens at the cost of reduced performance or (2) set + capacity factor to number of experts and thus waste computation + and memory on padding. + """ + + def __init__(self, config): + super().__init__() + self.hidden_dim = config.hidden_size + self.ffn_dim = config.intermediate_size + self.num_experts = config.num_local_experts + self.top_k = config.num_experts_per_tok + self.router = PhimoeTopKRouter(config) + self.experts = PhimoeExperts(config) + self.input_jitter_noise = config.input_jitter_noise + + def forward(self, hidden_states: torch.Tensor) -> torch.Tensor: + batch_size, sequence_length, hidden_dim = hidden_states.shape + if self.training and self.input_jitter_noise > 0: + hidden_states *= torch.empty_like(hidden_states).uniform_( + 1.0 - self.input_jitter_noise, 1.0 + self.input_jitter_noise + ) + + batch_size, sequence_length, hidden_dim = hidden_states.shape + hidden_states = hidden_states.reshape(-1, hidden_dim) + _, routing_weights, selected_experts = self.router(hidden_states) + final_hidden_states = self.experts(hidden_states, selected_experts, routing_weights) + return final_hidden_states.reshape(batch_size, sequence_length, hidden_dim) + + +class PhimoeDecoderLayer(MixtralDecoderLayer): + def __init__(self, config: PhimoeConfig, layer_idx: int): + super().__init__(config, layer_idx) + + # Phimoe uses nn.LayerNorm + self.input_layernorm = nn.LayerNorm(config.hidden_size, eps=config.rms_norm_eps, elementwise_affine=True) + self.post_attention_layernorm = nn.LayerNorm( + config.hidden_size, eps=config.rms_norm_eps, elementwise_affine=True + ) + + +class PhimoePreTrainedModel(MixtralPreTrainedModel): + _can_record_outputs = { + "router_logits": OutputRecorder(PhimoeTopKRouter, index=0), + "hidden_states": PhimoeDecoderLayer, + "attentions": PhimoeAttention, + } + + +class PhimoeModel(MixtralModel): + def __init__(self, config: PhimoeConfig): + super().__init__(config) + self.norm = nn.LayerNorm(config.hidden_size, eps=config.rms_norm_eps, elementwise_affine=True) + + +class PhimoeForCausalLM(MixtralForCausalLM): + def __init__(self, config): + super().__init__(config) + self.lm_head = nn.Linear(config.hidden_size, config.vocab_size, bias=self.config.lm_head_bias) + + # Copied from transformers.models.phi3.modeling_phi3.Phi3ForCausalLM.prepare_inputs_for_generation + def prepare_inputs_for_generation( + self, + input_ids, + past_key_values=None, + attention_mask=None, + inputs_embeds=None, + cache_position=None, + position_ids=None, + use_cache=True, + logits_to_keep=None, + **kwargs, + ): + # Overwritten -- this model may need to switch between short and long rope, invalidating the cache in the + # process + + # When the first time input length reached long and short factor switching point, enforce re-compute cache + # It will cause downside of slower at this single token position, however, better than current failure. + if ( + past_key_values + and hasattr(self.config, "original_max_position_embeddings") + and input_ids.shape[1] >= self.config.original_max_position_embeddings + 1 + ): + past_length = cache_position[0] + if past_length <= self.config.original_max_position_embeddings: + past_key_values = None + + model_inputs = super().prepare_inputs_for_generation( + input_ids=input_ids, + past_key_values=past_key_values, + attention_mask=attention_mask, + inputs_embeds=inputs_embeds, + cache_position=cache_position, + position_ids=position_ids, + use_cache=use_cache, + logits_to_keep=logits_to_keep, + **kwargs, + ) + return model_inputs + + +class PhimoeForSequenceClassification(GenericForSequenceClassification, PhimoePreTrainedModel): ... + + +__all__ = [ + "PhimoePreTrainedModel", + "PhimoeModel", + "PhimoeForCausalLM", + "PhimoeForSequenceClassification", +] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/phobert/__init__.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/phobert/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..5c14d34aff61362159e0b45e5895ceb08850faf5 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/phobert/__init__.py @@ -0,0 +1,26 @@ +# Copyright 2024 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from typing import TYPE_CHECKING + +from ...utils import _LazyModule +from ...utils.import_utils import define_import_structure + + +if TYPE_CHECKING: + from .tokenization_phobert import * +else: + import sys + + _file = globals()["__file__"] + sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__) diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/phobert/tokenization_phobert.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/phobert/tokenization_phobert.py new file mode 100644 index 0000000000000000000000000000000000000000..6dd66b7da72d507405e49d1ec1534e160b6215a7 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/phobert/tokenization_phobert.py @@ -0,0 +1,349 @@ +# Copyright (c) 2020, VinAI Research and the HuggingFace Inc. team. +# Copyright 2018 The Open AI Team Authors and The HuggingFace Inc. team. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""Tokenization classes for PhoBERT""" + +import os +import re +from shutil import copyfile + +from ...tokenization_python import PreTrainedTokenizer +from ...utils import logging + + +logger = logging.get_logger(__name__) + +VOCAB_FILES_NAMES = { + "vocab_file": "vocab.txt", + "merges_file": "bpe.codes", +} + + +def get_pairs(word): + """ + Return set of symbol pairs in a word. + + Word is represented as tuple of symbols (symbols being variable-length strings). + """ + pairs = set() + prev_char = word[0] + for char in word[1:]: + pairs.add((prev_char, char)) + prev_char = char + + pairs = set(pairs) + return pairs + + +class PhobertTokenizer(PreTrainedTokenizer): + """ + Construct a PhoBERT tokenizer. Based on Byte-Pair-Encoding. + + This tokenizer inherits from [`PreTrainedTokenizer`] which contains most of the main methods. Users should refer to + this superclass for more information regarding those methods. + + Args: + vocab_file (`str`): + Path to the vocabulary file. + merges_file (`str`): + Path to the merges file. + bos_token (`st`, *optional*, defaults to `""`): + The beginning of sequence token that was used during pretraining. Can be used a sequence classifier token. + + + + When building a sequence using special tokens, this is not the token that is used for the beginning of + sequence. The token used is the `cls_token`. + + + + eos_token (`str`, *optional*, defaults to `""`): + The end of sequence token. + + + + When building a sequence using special tokens, this is not the token that is used for the end of sequence. + The token used is the `sep_token`. + + + + sep_token (`str`, *optional*, defaults to `""`): + The separator token, which is used when building a sequence from multiple sequences, e.g. two sequences for + sequence classification or for a text and a question for question answering. It is also used as the last + token of a sequence built with special tokens. + cls_token (`str`, *optional*, defaults to `""`): + The classifier token which is used when doing sequence classification (classification of the whole sequence + instead of per-token classification). It is the first token of the sequence when built with special tokens. + unk_token (`str`, *optional*, defaults to `""`): + The unknown token. A token that is not in the vocabulary cannot be converted to an ID and is set to be this + token instead. + pad_token (`str`, *optional*, defaults to `""`): + The token used for padding, for example when batching sequences of different lengths. + mask_token (`str`, *optional*, defaults to `""`): + The token used for masking values. This is the token used when training this model with masked language + modeling. This is the token which the model will try to predict. + """ + + vocab_files_names = VOCAB_FILES_NAMES + + def __init__( + self, + vocab_file, + merges_file, + bos_token="", + eos_token="", + sep_token="", + cls_token="", + unk_token="", + pad_token="", + mask_token="", + **kwargs, + ): + self.vocab_file = vocab_file + self.merges_file = merges_file + + self.encoder = {} + self.encoder[str(bos_token)] = 0 + self.encoder[str(pad_token)] = 1 + self.encoder[str(eos_token)] = 2 + self.encoder[str(unk_token)] = 3 + + self.add_from_file(vocab_file) + + self.decoder = {v: k for k, v in self.encoder.items()} + + with open(merges_file, encoding="utf-8") as merges_handle: + merges = merges_handle.read().split("\n")[:-1] + merges = [tuple(merge.split()[:-1]) for merge in merges] + + self.bpe_ranks = dict(zip(merges, range(len(merges)))) + self.cache = {} + + super().__init__( + bos_token=bos_token, + eos_token=eos_token, + unk_token=unk_token, + sep_token=sep_token, + cls_token=cls_token, + pad_token=pad_token, + mask_token=mask_token, + **kwargs, + ) + + def build_inputs_with_special_tokens( + self, token_ids_0: list[int], token_ids_1: list[int] | None = None + ) -> list[int]: + """ + Build model inputs from a sequence or a pair of sequence for sequence classification tasks by concatenating and + adding special tokens. A PhoBERT sequence has the following format: + + - single sequence: ` X ` + - pair of sequences: ` A B ` + + Args: + token_ids_0 (`list[int]`): + List of IDs to which the special tokens will be added. + token_ids_1 (`list[int]`, *optional*): + Optional second list of IDs for sequence pairs. + + Returns: + `list[int]`: List of [input IDs](../glossary#input-ids) with the appropriate special tokens. + """ + + if token_ids_1 is None: + return [self.cls_token_id] + token_ids_0 + [self.sep_token_id] + cls = [self.cls_token_id] + sep = [self.sep_token_id] + return cls + token_ids_0 + sep + sep + token_ids_1 + sep + + def get_special_tokens_mask( + self, token_ids_0: list[int], token_ids_1: list[int] | None = None, already_has_special_tokens: bool = False + ) -> list[int]: + """ + Retrieve sequence ids from a token list that has no special tokens added. This method is called when adding + special tokens using the tokenizer `prepare_for_model` method. + + Args: + token_ids_0 (`list[int]`): + List of IDs. + token_ids_1 (`list[int]`, *optional*): + Optional second list of IDs for sequence pairs. + already_has_special_tokens (`bool`, *optional*, defaults to `False`): + Whether or not the token list is already formatted with special tokens for the model. + + Returns: + `list[int]`: A list of integers in the range [0, 1]: 1 for a special token, 0 for a sequence token. + """ + + if already_has_special_tokens: + return super().get_special_tokens_mask( + token_ids_0=token_ids_0, token_ids_1=token_ids_1, already_has_special_tokens=True + ) + + if token_ids_1 is None: + return [1] + ([0] * len(token_ids_0)) + [1] + return [1] + ([0] * len(token_ids_0)) + [1, 1] + ([0] * len(token_ids_1)) + [1] + + def create_token_type_ids_from_sequences( + self, token_ids_0: list[int], token_ids_1: list[int] | None = None + ) -> list[int]: + """ + Create a mask from the two sequences passed to be used in a sequence-pair classification task. PhoBERT does not + make use of token type ids, therefore a list of zeros is returned. + + Args: + token_ids_0 (`list[int]`): + List of IDs. + token_ids_1 (`list[int]`, *optional*): + Optional second list of IDs for sequence pairs. + + Returns: + `list[int]`: List of zeros. + """ + + sep = [self.sep_token_id] + cls = [self.cls_token_id] + + if token_ids_1 is None: + return len(cls + token_ids_0 + sep) * [0] + return len(cls + token_ids_0 + sep + sep + token_ids_1 + sep) * [0] + + @property + def vocab_size(self): + return len(self.encoder) + + def get_vocab(self): + return dict(self.encoder, **self.added_tokens_encoder) + + def bpe(self, token): + if token in self.cache: + return self.cache[token] + word = tuple(token) + word = tuple(list(word[:-1]) + [word[-1] + ""]) + pairs = get_pairs(word) + + if not pairs: + return token + + while True: + bigram = min(pairs, key=lambda pair: self.bpe_ranks.get(pair, float("inf"))) + if bigram not in self.bpe_ranks: + break + first, second = bigram + new_word = [] + i = 0 + while i < len(word): + try: + j = word.index(first, i) + except ValueError: + new_word.extend(word[i:]) + break + else: + new_word.extend(word[i:j]) + i = j + + if word[i] == first and i < len(word) - 1 and word[i + 1] == second: + new_word.append(first + second) + i += 2 + else: + new_word.append(word[i]) + i += 1 + new_word = tuple(new_word) + word = new_word + if len(word) == 1: + break + else: + pairs = get_pairs(word) + word = "@@ ".join(word) + word = word[:-4] + self.cache[token] = word + return word + + def _tokenize(self, text): + """Tokenize a string.""" + split_tokens = [] + + words = re.findall(r"\S+\n?", text) + + for token in words: + split_tokens.extend(list(self.bpe(token).split(" "))) + return split_tokens + + def _convert_token_to_id(self, token): + """Converts a token (str) in an id using the vocab.""" + return self.encoder.get(token, self.encoder.get(self.unk_token)) + + def _convert_id_to_token(self, index): + """Converts an index (integer) in a token (str) using the vocab.""" + return self.decoder.get(index, self.unk_token) + + def convert_tokens_to_string(self, tokens): + """Converts a sequence of tokens (string) in a single string.""" + out_string = " ".join(tokens).replace("@@ ", "").strip() + return out_string + + def save_vocabulary(self, save_directory: str, filename_prefix: str | None = None) -> tuple[str]: + if not os.path.isdir(save_directory): + logger.error(f"Vocabulary path ({save_directory}) should be a directory") + return + out_vocab_file = os.path.join( + save_directory, (filename_prefix + "-" if filename_prefix else "") + VOCAB_FILES_NAMES["vocab_file"] + ) + out_merge_file = os.path.join( + save_directory, (filename_prefix + "-" if filename_prefix else "") + VOCAB_FILES_NAMES["merges_file"] + ) + + if os.path.abspath(self.vocab_file) != os.path.abspath(out_vocab_file) and os.path.isfile(self.vocab_file): + copyfile(self.vocab_file, out_vocab_file) + elif not os.path.isfile(self.vocab_file): + with open(out_vocab_file, "wb") as fi: + content_spiece_model = self.sp_model.serialized_model_proto() + fi.write(content_spiece_model) + + if os.path.abspath(self.merges_file) != os.path.abspath(out_merge_file): + copyfile(self.merges_file, out_merge_file) + + return out_vocab_file, out_merge_file + + # def decode(self, token_ids, skip_special_tokens=False, clean_up_tokenization_spaces=True): + # filtered_tokens = ' '.join(self.convert_ids_to_tokens(token_ids, skip_special_tokens=skip_special_tokens)) + # tokens_generated_so_far = re.sub('(@@ )', '', string=filtered_tokens) + # tokens_generated_so_far = re.sub('(@@ ?$)', '', string=tokens_generated_so_far) + # return ''.join(tokens_generated_so_far) + + def add_from_file(self, f): + """ + Loads a pre-existing dictionary from a text file and adds its symbols to this instance. + """ + if isinstance(f, str): + try: + with open(f, "r", encoding="utf-8") as fd: + self.add_from_file(fd) + except FileNotFoundError as fnfe: + raise fnfe + except UnicodeError: + raise Exception(f"Incorrect encoding detected in {f}, please rebuild the dataset") + return + + lines = f.readlines() + for lineTmp in lines: + line = lineTmp.strip() + idx = line.rfind(" ") + if idx == -1: + raise ValueError("Incorrect dictionary format, expected ' '") + word = line[:idx] + self.encoder[word] = len(self.encoder) + + +__all__ = ["PhobertTokenizer"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pix2struct/__init__.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pix2struct/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..7cf28e634b13d18369818b582d4e82127001586a --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pix2struct/__init__.py @@ -0,0 +1,30 @@ +# Copyright 2024 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from typing import TYPE_CHECKING + +from ...utils import _LazyModule +from ...utils.import_utils import define_import_structure + + +if TYPE_CHECKING: + from .configuration_pix2struct import * + from .image_processing_pix2struct import * + from .image_processing_pix2struct_fast import * + from .modeling_pix2struct import * + from .processing_pix2struct import * +else: + import sys + + _file = globals()["__file__"] + sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__) diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pix2struct/configuration_pix2struct.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pix2struct/configuration_pix2struct.py new file mode 100644 index 0000000000000000000000000000000000000000..fd03bbd06fbb841b6ecb9a3ddfcf1507f64463fa --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pix2struct/configuration_pix2struct.py @@ -0,0 +1,344 @@ +# Copyright 2023 The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""Pix2Struct model configuration""" + +from ...configuration_utils import PreTrainedConfig +from ...utils import logging + + +logger = logging.get_logger(__name__) + + +class Pix2StructTextConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`Pix2StructTextModel`]. It is used to instantiate + a Pix2Struct text model according to the specified arguments, defining the model architecture. Instantiating a + configuration with the defaults will yield a similar configuration to that of the Pix2Struct text decoder used by + the [google/pix2struct-base](https://huggingface.co/google/pix2struct-base) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + vocab_size (`int`, *optional*, defaults to 50244): + Vocabulary size of the `Pix2Struct` text model. Defines the number of different tokens that can be + represented by the `inputs_ids` passed when calling [`Pix2StructTextModel`]. + hidden_size (`int`, *optional*, defaults to 768): + Dimensionality of the encoder layers and the pooler layer. + d_kv (`int`, *optional*, defaults to 64): + Dimensionality of the key, query, value projections in each attention head. + d_ff (`int`, *optional*, defaults to 2048): + Dimensionality of the "intermediate" (i.e., feed-forward) layer in the Transformer encoder. + num_layers (`int`, *optional*, defaults to 12): + Number of hidden layers in the Transformer encoder. + num_heads (`int`, *optional*, defaults to 12): + Number of attention heads for each attention layer in the Transformer encoder. + relative_attention_num_buckets (`int`, *optional*, defaults to 32): + The number of buckets to use for each attention layer. + relative_attention_max_distance (`int`, *optional*, defaults to 128): + The maximum distance of the longer sequences for the bucket separation. + dropout_rate (`float`, *optional*, defaults to 0.1): + The dropout probability for all fully connected layers in the embeddings, encoder, and pooler. + layer_norm_epsilon (`float`, *optional*, defaults to 1e-6): + The epsilon used by the layer normalization layers. + initializer_factor (`float`, *optional*, defaults to 1.0): + A factor for initializing all weight matrices (should be kept to 1, used internally for initialization + testing). + dense_act_fn (`Union[Callable, str]`, *optional*, defaults to `"gelu_new"`): + The non-linear activation function (function or string). + decoder_start_token_id (`int`, *optional*, defaults to 0): + The id of the `decoder_start_token_id` token. + use_cache (`bool`, *optional*, defaults to `False`): + Whether or not the model should return the last key/values attentions (not used by all models). + pad_token_id (`int`, *optional*, defaults to 0): + The id of the `padding` token. + eos_token_id (`int`, *optional*, defaults to 1): + The id of the `end-of-sequence` token. + + Example: + + ```python + >>> from transformers import Pix2StructTextConfig, Pix2StructTextModel + + >>> # Initializing a Pix2StructTextConfig with google/pix2struct-base style configuration + >>> configuration = Pix2StructTextConfig() + + >>> # Initializing a Pix2StructTextModel (with random weights) from the google/pix2struct-base style configuration + >>> model = Pix2StructTextModel(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "pix2struct_text_model" + keys_to_ignore_at_inference = ["past_key_values"] + attribute_map = { + "hidden_size": "hidden_size", + "num_attention_heads": "num_heads", + "num_hidden_layers": "num_layers", + "decoder_attention_heads": "num_heads", + "encoder_attention_heads": "num_heads", + "encoder_layers": "num_layers", + "decoder_layers": "num_layers", + } + + def __init__( + self, + vocab_size=50244, + hidden_size=768, + d_kv=64, + d_ff=2048, + num_layers=12, + num_heads=12, + relative_attention_num_buckets=32, + relative_attention_max_distance=128, + dropout_rate=0.1, + layer_norm_epsilon=1e-6, + initializer_factor=1.0, + dense_act_fn="gelu_new", + decoder_start_token_id=0, + use_cache=False, + pad_token_id=0, + eos_token_id=1, + bos_token_id=None, + tie_word_embeddings=False, + is_decoder=True, + add_cross_attention=False, + **kwargs, + ): + self.vocab_size = vocab_size + self.hidden_size = hidden_size + self.d_kv = d_kv + self.d_ff = d_ff + self.num_layers = num_layers + self.num_heads = num_heads + self.relative_attention_num_buckets = relative_attention_num_buckets + self.relative_attention_max_distance = relative_attention_max_distance + self.dropout_rate = dropout_rate + self.layer_norm_epsilon = layer_norm_epsilon + self.initializer_factor = initializer_factor + self.use_cache = use_cache + + self.eos_token_id = eos_token_id + self.bos_token_id = bos_token_id + self.decoder_start_token_id = decoder_start_token_id + + # for backwards compatibility + self.dense_act_fn = dense_act_fn + + self.pad_token_id = pad_token_id + self.eos_token_id = eos_token_id + self.decoder_start_token_id = decoder_start_token_id + self.tie_word_embeddings = tie_word_embeddings + self.is_decoder = is_decoder + self.add_cross_attention = add_cross_attention + super().__init__(**kwargs) + + +class Pix2StructVisionConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`Pix2StructVisionModel`]. It is used to + instantiate a Pix2Struct vision model according to the specified arguments, defining the model architecture. + Instantiating a configuration defaults will yield a similar configuration to that of the Pix2Struct-base + [google/pix2struct-base](https://huggingface.co/google/pix2struct-base) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + hidden_size (`int`, *optional*, defaults to 768): + Dimensionality of the encoder layers and the pooler layer. + patch_embed_hidden_size (`int`, *optional*, defaults to 768): + Dimensionality of the input patch_embedding layer in the Transformer encoder. + d_ff (`int`, *optional*, defaults to 2048): + Dimensionality of the "intermediate" (i.e., feed-forward) layer in the Transformer encoder. + d_kv (`int`, *optional*, defaults to 64): + Dimensionality of the key, query, value projections per attention head. + num_hidden_layers (`int`, *optional*, defaults to 12): + Number of hidden layers in the Transformer encoder. + num_attention_heads (`int`, *optional*, defaults to 12): + Number of attention heads for each attention layer in the Transformer encoder. + dense_act_fn (`str` or `function`, *optional*, defaults to `"gelu_new"`): + The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`, + `"relu"`, `"selu"` and `"gelu_new"` `"gelu"` are supported. + layer_norm_eps (`float`, *optional*, defaults to 1e-06): + The epsilon used by the layer normalization layers. + dropout_rate (`float`, *optional*, defaults to 0.0): + The dropout probability for all fully connected layers in the embeddings, encoder, and pooler. + attention_dropout (`float`, *optional*, defaults to 0.0): + The dropout ratio for the attention probabilities. + initializer_range (`float`, *optional*, defaults to 1e-10): + The standard deviation of the truncated_normal_initializer for initializing all weight matrices. + initializer_factor (`float`, *optional*, defaults to 1.0): + A factor for initializing all weight matrices (should be kept to 1, used internally for initialization + testing). + seq_len (`int`, *optional*, defaults to 4096): + Maximum sequence length (here number of patches) supported by the model. + relative_attention_num_buckets (`int`, *optional*, defaults to 32): + The number of buckets to use for each attention layer. + relative_attention_max_distance (`int`, *optional*, defaults to 128): + The maximum distance (in tokens) to use for each attention layer. + + Example: + + ```python + >>> from transformers import Pix2StructVisionConfig, Pix2StructVisionModel + + >>> # Initializing a Pix2StructVisionConfig with google/pix2struct-base style configuration + >>> configuration = Pix2StructVisionConfig() + + >>> # Initializing a Pix2StructVisionModel (with random weights) from the google/pix2struct-base style configuration + >>> model = Pix2StructVisionModel(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "pix2struct_vision_model" + + def __init__( + self, + hidden_size=768, + patch_embed_hidden_size=768, + d_ff=2048, + d_kv=64, + num_hidden_layers=12, + num_attention_heads=12, + dense_act_fn="gelu_new", + layer_norm_eps=1e-6, + dropout_rate=0.0, + attention_dropout=0.0, + initializer_range=1e-10, + initializer_factor=1.0, + seq_len=4096, + relative_attention_num_buckets=32, + relative_attention_max_distance=128, + **kwargs, + ): + super().__init__(**kwargs) + + self.hidden_size = hidden_size + self.patch_embed_hidden_size = patch_embed_hidden_size + self.d_ff = d_ff + self.dropout_rate = dropout_rate + self.num_hidden_layers = num_hidden_layers + self.num_attention_heads = num_attention_heads + self.initializer_range = initializer_range + self.initializer_factor = initializer_factor + self.attention_dropout = attention_dropout + self.layer_norm_eps = layer_norm_eps + self.dense_act_fn = dense_act_fn + self.seq_len = seq_len + self.relative_attention_num_buckets = relative_attention_num_buckets + self.relative_attention_max_distance = relative_attention_max_distance + self.d_kv = d_kv + + +class Pix2StructConfig(PreTrainedConfig): + r""" + [`Pix2StructConfig`] is the configuration class to store the configuration of a + [`Pix2StructForConditionalGeneration`]. It is used to instantiate a Pix2Struct model according to the specified + arguments, defining the text model and vision model configs. Instantiating a configuration with the defaults will + yield a similar configuration to that of the Pix2Struct-base + [google/pix2struct-base](https://huggingface.co/google/pix2struct-base) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + text_config (`dict`, *optional*): + Dictionary of configuration options used to initialize [`Pix2StructTextConfig`]. + vision_config (`dict`, *optional*): + Dictionary of configuration options used to initialize [`Pix2StructVisionConfig`]. + initializer_factor (`float`, *optional*, defaults to 1.0): + Factor to multiply the initialization range with. + initializer_range (`float`, *optional*, defaults to 0.02): + The standard deviation of the truncated_normal_initializer for initializing all weight matrices. + is_vqa (`bool`, *optional*, defaults to `False`): + Whether the model has been fine-tuned for VQA or not. + kwargs (*optional*): + Dictionary of keyword arguments. + + Example: + + ```python + >>> from transformers import Pix2StructConfig, Pix2StructForConditionalGeneration + + >>> # Initializing a Pix2StructConfig with google/pix2struct-base style configuration + >>> configuration = Pix2StructConfig() + + >>> # Initializing a Pix2StructForConditionalGeneration (with random weights) from the google/pix2struct-base style configuration + >>> model = Pix2StructForConditionalGeneration(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + + >>> # We can also initialize a Pix2StructConfig from a Pix2StructTextConfig and a Pix2StructVisionConfig + + >>> # Initializing a Pix2Struct text and Pix2Struct vision configuration + >>> config_text = Pix2StructTextConfig() + >>> config_vision = Pix2StructVisionConfig() + + >>> config = Pix2StructConfig(text_config=config_text, vision_config=config_vision) + ```""" + + model_type = "pix2struct" + sub_configs = {"text_config": Pix2StructTextConfig, "vision_config": Pix2StructVisionConfig} + + def __init__( + self, + text_config=None, + vision_config=None, + initializer_factor=1.0, + initializer_range=0.02, + is_vqa=False, + tie_word_embeddings=False, + is_encoder_decoder=True, + **kwargs, + ): + if text_config is None: + text_config = Pix2StructTextConfig( + {"is_encoder_decoder": is_encoder_decoder, "tie_word_embeddings": tie_word_embeddings} + ) + logger.info("`text_config` is `None`. initializing the `Pix2StructTextConfig` with default values.") + elif isinstance(text_config, dict): + text_config["is_encoder_decoder"] = is_encoder_decoder + text_config["tie_word_embeddings"] = tie_word_embeddings + text_config = Pix2StructTextConfig(**text_config) + + if vision_config is None: + vision_config = Pix2StructVisionConfig() + logger.info("`vision_config` is `None`. initializing the `Pix2StructVisionConfig` with default values.") + elif isinstance(vision_config, dict): + vision_config = Pix2StructVisionConfig(**vision_config) + + self.text_config = text_config + self.vision_config = vision_config + + self.decoder_start_token_id = self.text_config.decoder_start_token_id + self.pad_token_id = self.text_config.pad_token_id + self.eos_token_id = self.text_config.eos_token_id + + self.initializer_factor = initializer_factor + self.initializer_range = initializer_range + + self.text_config.initializer_range = self.initializer_range + self.vision_config.initializer_range = self.initializer_range + + self.is_vqa = is_vqa + self.tie_word_embeddings = tie_word_embeddings + super().__init__(is_encoder_decoder=is_encoder_decoder, **kwargs) + + +__all__ = ["Pix2StructConfig", "Pix2StructTextConfig", "Pix2StructVisionConfig"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pix2struct/image_processing_pix2struct.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pix2struct/image_processing_pix2struct.py new file mode 100644 index 0000000000000000000000000000000000000000..45e68cdb788eca375a6dd674937c41ce2e779ca3 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pix2struct/image_processing_pix2struct.py @@ -0,0 +1,470 @@ +# Copyright 2023 The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""Image processor class for Pix2Struct.""" + +import io +import math + +import numpy as np +from huggingface_hub import hf_hub_download + +from ...image_processing_utils import BaseImageProcessor, BatchFeature +from ...image_transforms import convert_to_rgb, normalize, to_channel_dimension_format, to_pil_image +from ...image_utils import ( + ChannelDimension, + ImageInput, + get_image_size, + infer_channel_dimension_format, + make_flat_list_of_images, + to_numpy_array, + valid_images, +) +from ...processing_utils import ImagesKwargs +from ...utils import TensorType, is_torch_available, is_vision_available, logging +from ...utils.import_utils import requires_backends + + +if is_vision_available(): + import textwrap + + from PIL import Image, ImageDraw, ImageFont + +if is_torch_available(): + import torch + +logger = logging.get_logger(__name__) +DEFAULT_FONT_PATH = "ybelkada/fonts" + + +class Pix2StructImageProcessorKwargs(ImagesKwargs, total=False): + """ + max_patches (`int`, *optional*): + Maximum number of patches to extract. + patch_size (`dict[str, int]`, *optional*, defaults to `{"height": 16, "width": 16}`): + The patch size to use for the image. According to Pix2Struct paper and code, the patch size is 16x16. + is_vqa (`bool`, *optional*, defaults to `False`): + Whether or not the image processor is for the VQA task. If `True` and `header_text` is passed in, text is + rendered onto the input images. + header_text (`Union[list[str], str]`, *optional*): + Text to render as a header. Only has an effect if `image_processor.is_vqa` is `True`. + """ + + max_patches: int + patch_size: dict[str, int] + is_vqa: bool + header_text: list[str] | str | None + + +# adapted from: https://discuss.pytorch.org/t/tf-image-extract-patches-in-pytorch/171409/2 +def torch_extract_patches(image_tensor, patch_height, patch_width): + """ + Utility function to extract patches from a given image tensor. Returns a tensor of shape + (1, `rows`, `columns`, `num_channels`x `patch_height` x `patch_width`). + + Args: + image_tensor (torch.Tensor): + The image tensor to extract patches from. + patch_height (int): + The height of the patches to extract. + patch_width (int): + The width of the patches to extract. + """ + requires_backends(torch_extract_patches, ["torch"]) + + image_tensor = image_tensor.unsqueeze(0) + patches = torch.nn.functional.unfold(image_tensor, (patch_height, patch_width), stride=(patch_height, patch_width)) + patches = patches.reshape(image_tensor.size(0), image_tensor.size(1), patch_height, patch_width, -1) + patches = patches.permute(0, 4, 2, 3, 1).reshape( + image_tensor.size(2) // patch_height, + image_tensor.size(3) // patch_width, + image_tensor.size(1) * patch_height * patch_width, + ) + return patches.unsqueeze(0) + + +# Adapted from https://github.com/google-research/pix2struct/blob/0e1779af0f4db4b652c1d92b3bbd2550a7399123/pix2struct/preprocessing/preprocessing_utils.py#L106 +def render_text( + text: str, + text_size: int = 36, + text_color: str = "black", + background_color: str = "white", + left_padding: int = 5, + right_padding: int = 5, + top_padding: int = 5, + bottom_padding: int = 5, + font_bytes: bytes | None = None, + font_path: str | None = None, +) -> Image.Image: + """ + Render text. This script is entirely adapted from the original script that can be found here: + https://github.com/google-research/pix2struct/blob/main/pix2struct/preprocessing/preprocessing_utils.py + + Args: + text (`str`, *optional*, defaults to ): + Text to render. + text_size (`int`, *optional*, defaults to 36): + Size of the text. + text_color (`str`, *optional*, defaults to `"black"`): + Color of the text. + background_color (`str`, *optional*, defaults to `"white"`): + Color of the background. + left_padding (`int`, *optional*, defaults to 5): + Padding on the left. + right_padding (`int`, *optional*, defaults to 5): + Padding on the right. + top_padding (`int`, *optional*, defaults to 5): + Padding on the top. + bottom_padding (`int`, *optional*, defaults to 5): + Padding on the bottom. + font_bytes (`bytes`, *optional*): + Bytes of the font to use. If `None`, the default font will be used. + font_path (`str`, *optional*): + Path to the font to use. If `None`, the default font will be used. + """ + requires_backends(render_text, "vision") + # Add new lines so that each line is no more than 80 characters. + + wrapper = textwrap.TextWrapper(width=80) + lines = wrapper.wrap(text=text) + wrapped_text = "\n".join(lines) + + if font_bytes is not None and font_path is None: + font = io.BytesIO(font_bytes) + elif font_path is not None: + font = font_path + else: + font = hf_hub_download(DEFAULT_FONT_PATH, "Arial.TTF") + font = ImageFont.truetype(font, encoding="UTF-8", size=text_size) + + # Use a temporary canvas to determine the width and height in pixels when + # rendering the text. + temp_draw = ImageDraw.Draw(Image.new("RGB", (1, 1), background_color)) + _, _, text_width, text_height = temp_draw.textbbox((0, 0), wrapped_text, font) + + # Create the actual image with a bit of padding around the text. + image_width = text_width + left_padding + right_padding + image_height = text_height + top_padding + bottom_padding + image = Image.new("RGB", (image_width, image_height), background_color) + draw = ImageDraw.Draw(image) + draw.text(xy=(left_padding, top_padding), text=wrapped_text, fill=text_color, font=font) + return image + + +# Adapted from https://github.com/google-research/pix2struct/blob/0e1779af0f4db4b652c1d92b3bbd2550a7399123/pix2struct/preprocessing/preprocessing_utils.py#L87 +def render_header(image: np.ndarray, header: str, input_data_format: str | ChildProcessError | None = None, **kwargs): + """ + Renders the input text as a header on the input image. + + Args: + image (`np.ndarray`): + The image to render the header on. + header (`str`): + The header text. + data_format (`Union[ChannelDimension, str]`, *optional*): + The data format of the image. Can be either "ChannelDimension.channels_first" or + "ChannelDimension.channels_last". + + Returns: + `np.ndarray`: The image with the header rendered. + """ + requires_backends(render_header, "vision") + + # Convert to PIL image if necessary + image = to_pil_image(image, input_data_format=input_data_format) + + header_image = render_text(header, **kwargs) + new_width = max(header_image.width, image.width) + + new_height = int(image.height * (new_width / image.width)) + new_header_height = int(header_image.height * (new_width / header_image.width)) + + new_image = Image.new("RGB", (new_width, new_height + new_header_height), "white") + new_image.paste(header_image.resize((new_width, new_header_height)), (0, 0)) + new_image.paste(image.resize((new_width, new_height)), (0, new_header_height)) + + # Convert back to the original framework if necessary + new_image = to_numpy_array(new_image) + + if infer_channel_dimension_format(new_image) == ChannelDimension.LAST: + new_image = to_channel_dimension_format(new_image, ChannelDimension.LAST) + + return new_image + + +class Pix2StructImageProcessor(BaseImageProcessor): + r""" + Constructs a Pix2Struct image processor. + + Args: + do_convert_rgb (`bool`, *optional*, defaults to `True`): + Whether to convert the image to RGB. + do_normalize (`bool`, *optional*, defaults to `True`): + Whether to normalize the image. Can be overridden by the `do_normalize` parameter in the `preprocess` + method. According to Pix2Struct paper and code, the image is normalized with its own mean and standard + deviation. + patch_size (`dict[str, int]`, *optional*, defaults to `{"height": 16, "width": 16}`): + The patch size to use for the image. According to Pix2Struct paper and code, the patch size is 16x16. + max_patches (`int`, *optional*, defaults to 2048): + The maximum number of patches to extract from the image as per the [Pix2Struct + paper](https://huggingface.co/papers/2210.03347). + is_vqa (`bool`, *optional*, defaults to `False`): + Whether or not the image processor is for the VQA task. If `True` and `header_text` is passed in, text is + rendered onto the input images. + """ + + model_input_names = ["flattened_patches", "attention_mask"] + valid_kwargs = Pix2StructImageProcessorKwargs + + def __init__( + self, + do_convert_rgb: bool = True, + do_normalize: bool = True, + patch_size: dict[str, int] | None = None, + max_patches: int = 2048, + is_vqa: bool = False, + **kwargs, + ) -> None: + super().__init__(**kwargs) + self.patch_size = patch_size if patch_size is not None else {"height": 16, "width": 16} + self.do_normalize = do_normalize + self.do_convert_rgb = do_convert_rgb + self.max_patches = max_patches + self.is_vqa = is_vqa + + def extract_flattened_patches( + self, + image: np.ndarray, + max_patches: int, + patch_size: dict, + input_data_format: str | ChannelDimension | None = None, + **kwargs, + ) -> np.ndarray: + """ + Extract flattened patches from an image. + + Args: + image (`np.ndarray`): + Image to extract flattened patches from. + max_patches (`int`): + Maximum number of patches to extract. + patch_size (`dict`): + Dictionary containing the patch height and width. + + Returns: + result (`np.ndarray`): + A sequence of `max_patches` flattened patches. + """ + requires_backends(self.extract_flattened_patches, "torch") + + # convert to torch + image = to_channel_dimension_format(image, ChannelDimension.FIRST, input_data_format) + image = torch.from_numpy(image) + + patch_height, patch_width = patch_size["height"], patch_size["width"] + image_height, image_width = get_image_size(image, ChannelDimension.FIRST) + + # maximize scale s.t. + scale = math.sqrt(max_patches * (patch_height / image_height) * (patch_width / image_width)) + num_feasible_rows = max(min(math.floor(scale * image_height / patch_height), max_patches), 1) + num_feasible_cols = max(min(math.floor(scale * image_width / patch_width), max_patches), 1) + resized_height = max(num_feasible_rows * patch_height, 1) + resized_width = max(num_feasible_cols * patch_width, 1) + + image = torch.nn.functional.interpolate( + image.unsqueeze(0), + size=(resized_height, resized_width), + mode="bilinear", + align_corners=False, + antialias=True, + ).squeeze(0) + + # [1, rows, columns, patch_height * patch_width * image_channels] + patches = torch_extract_patches(image, patch_height, patch_width) + + patches_shape = patches.shape + rows = patches_shape[1] + columns = patches_shape[2] + depth = patches_shape[3] + + # [rows * columns, patch_height * patch_width * image_channels] + patches = patches.reshape([rows * columns, depth]) + + # [rows * columns, 1] + row_ids = torch.arange(rows).reshape([rows, 1]).repeat(1, columns).reshape([rows * columns, 1]) + col_ids = torch.arange(columns).reshape([1, columns]).repeat(rows, 1).reshape([rows * columns, 1]) + + # Offset by 1 so the ids do not contain zeros, which represent padding. + row_ids += 1 + col_ids += 1 + + # Prepare additional patch features. + # [rows * columns, 1] + row_ids = row_ids.to(torch.float32) + col_ids = col_ids.to(torch.float32) + + # [rows * columns, 2 + patch_height * patch_width * image_channels] + result = torch.cat([row_ids, col_ids, patches], -1) + + # [max_patches, 2 + patch_height * patch_width * image_channels] + result = torch.nn.functional.pad(result, [0, 0, 0, max_patches - (rows * columns)]).float() + + result = to_numpy_array(result) + + return result + + def normalize( + self, + image: np.ndarray, + data_format: str | ChannelDimension | None = None, + input_data_format: str | ChannelDimension | None = None, + **kwargs, + ) -> np.ndarray: + """ + Normalize an image. image = (image - image_mean) / image_std. + + Args: + image (`np.ndarray`): + Image to normalize. + data_format (`str` or `ChannelDimension`, *optional*): + The channel dimension format for the output image. If unset, the channel dimension format of the input + image is used. + input_data_format (`str` or `ChannelDimension`, *optional*): + The channel dimension format of the input image. If not provided, it will be inferred. + """ + if image.dtype == np.uint8: + image = image.astype(np.float32) + + # take mean across the whole `image` + mean = np.mean(image) + std = np.std(image) + adjusted_stddev = max(std, 1.0 / math.sqrt(np.prod(image.shape))) + + return normalize( + image, + mean=mean, + std=adjusted_stddev, + data_format=data_format, + input_data_format=input_data_format, + **kwargs, + ) + + def preprocess( + self, + images: ImageInput, + header_text: str | None = None, + do_convert_rgb: bool | None = None, + do_normalize: bool | None = None, + max_patches: int | None = None, + patch_size: dict[str, int] | None = None, + return_tensors: str | TensorType | None = None, + data_format: ChannelDimension = ChannelDimension.FIRST, + input_data_format: str | ChannelDimension | None = None, + **kwargs, + ) -> ImageInput: + """ + Preprocess an image or batch of images. The processor first computes the maximum possible number of + aspect-ratio preserving patches of size `patch_size` that can be extracted from the image. It then pads the + image with zeros to make the image respect the constraint of `max_patches`. + + Args: + images (`ImageInput`): + Image to preprocess. Expects a single or batch of images. + header_text (`Union[list[str], str]`, *optional*): + Text to render as a header. Only has an effect if `image_processor.is_vqa` is `True`. + do_convert_rgb (`bool`, *optional*, defaults to `self.do_convert_rgb`): + Whether to convert the image to RGB. + do_normalize (`bool`, *optional*, defaults to `self.do_normalize`): + Whether to normalize the image. + max_patches (`int`, *optional*, defaults to `self.max_patches`): + Maximum number of patches to extract. + patch_size (`dict`, *optional*, defaults to `self.patch_size`): + Dictionary containing the patch height and width. + return_tensors (`str` or `TensorType`, *optional*): + The type of tensors to return. Can be one of: + - Unset: Return a list of `np.ndarray`. + - `TensorType.PYTORCH` or `'pt'`: Return a batch of type `torch.Tensor`. + - `TensorType.NUMPY` or `'np'`: Return a batch of type `np.ndarray`. + data_format (`ChannelDimension` or `str`, *optional*, defaults to `ChannelDimension.FIRST`): + The channel dimension format for the output image. Can be one of: + - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format. + - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format. + - Unset: Use the channel dimension format of the input image. + input_data_format (`ChannelDimension` or `str`, *optional*): + The channel dimension format for the input image. If unset, the channel dimension format is inferred + from the input image. Can be one of: + - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format. + - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format. + - `"none"` or `ChannelDimension.NONE`: image in (height, width) format. + """ + do_normalize = do_normalize if do_normalize is not None else self.do_normalize + do_convert_rgb = do_convert_rgb if do_convert_rgb is not None else self.do_convert_rgb + patch_size = patch_size if patch_size is not None else self.patch_size + max_patches = max_patches if max_patches is not None else self.max_patches + is_vqa = self.is_vqa + + if kwargs.get("data_format") is not None: + raise ValueError("data_format is not an accepted input as the outputs are ") + + images = make_flat_list_of_images(images) + + if not valid_images(images): + raise ValueError("Invalid image type. Must be of type PIL.Image.Image, numpy.ndarray, or torch.Tensor") + + # PIL RGBA images are converted to RGB + if do_convert_rgb: + images = [convert_to_rgb(image) for image in images] + + # All transformations expect numpy arrays. + images = [to_numpy_array(image) for image in images] + + if input_data_format is None: + # We assume that all images have the same channel dimension format. + input_data_format = infer_channel_dimension_format(images[0]) + + if is_vqa: + if header_text is None: + raise ValueError("A header text must be provided for VQA models.") + font_bytes = kwargs.pop("font_bytes", None) + font_path = kwargs.pop("font_path", None) + + if isinstance(header_text, str): + header_text = [header_text] * len(images) + + images = [ + render_header(image, header_text[i], font_bytes=font_bytes, font_path=font_path) + for i, image in enumerate(images) + ] + + if do_normalize: + images = [self.normalize(image=image, input_data_format=input_data_format) for image in images] + + # convert to torch tensor and permute + images = [ + self.extract_flattened_patches( + image=image, max_patches=max_patches, patch_size=patch_size, input_data_format=input_data_format + ) + for image in images + ] + + # create attention mask in numpy + attention_masks = [(image.sum(axis=-1) != 0).astype(np.float32) for image in images] + + encoded_outputs = BatchFeature( + data={"flattened_patches": images, "attention_mask": attention_masks}, tensor_type=return_tensors + ) + + return encoded_outputs + + +__all__ = ["Pix2StructImageProcessor"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pix2struct/image_processing_pix2struct_fast.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pix2struct/image_processing_pix2struct_fast.py new file mode 100644 index 0000000000000000000000000000000000000000..968eda8d9939cfd21def7dfc3910be8c07820b29 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pix2struct/image_processing_pix2struct_fast.py @@ -0,0 +1,336 @@ +# Copyright 2025 The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""Fast Image processor class for Pix2Struct.""" + +import torch +import torchvision.transforms.v2.functional as tvF +from PIL import Image + +from ...image_processing_utils import BatchFeature, get_size_dict +from ...image_processing_utils_fast import BaseImageProcessorFast +from ...image_transforms import group_images_by_shape, reorder_images +from ...image_utils import ChannelDimension, ImageInput, SizeDict +from ...processing_utils import Unpack +from ...utils import TensorType, auto_docstring +from .image_processing_pix2struct import Pix2StructImageProcessorKwargs, render_text + + +# Disable as it causes issues with torch.compile +@torch.compiler.disable +def torch_extract_patches(image_tensor, patch_height, patch_width): + """ + Extract patches from image tensor. Returns tensor of shape (batch, rows, columns, patch_height*patch_width*channels). + + Args: + image_tensor (`torch.Tensor`): + Image tensor of shape (batch, channels, height, width). + patch_height (`int`): + Height of patches to extract. + patch_width (`int`): + Width of patches to extract. + """ + batch_size, channels, height, width = image_tensor.shape + patches = torch.nn.functional.unfold(image_tensor, (patch_height, patch_width), stride=(patch_height, patch_width)) + patches = patches.reshape(batch_size, channels, patch_height, patch_width, -1) + patches = patches.permute(0, 4, 2, 3, 1).reshape( + batch_size, height // patch_height, width // patch_width, channels * patch_height * patch_width + ) + return patches + + +@auto_docstring +class Pix2StructImageProcessorFast(BaseImageProcessorFast): + rescale_factor = None + do_normalize = True + do_convert_rgb = True + patch_size = {"height": 16, "width": 16} + max_patches = 2048 + is_vqa = False + valid_kwargs = Pix2StructImageProcessorKwargs + model_input_names = ["flattened_patches", "attention_mask"] + + def _further_process_kwargs( + self, + patch_size: dict[str, int] | None = None, + **kwargs, + ) -> dict: + """ + Process custom Pix2Struct kwargs, specifically converting patch_size to SizeDict. + """ + # Call super to handle standard kwargs processing (like converting patch_size to SizeDict) + kwargs = super()._further_process_kwargs(**kwargs) + kwargs["patch_size"] = SizeDict(**get_size_dict(size=patch_size, param_name="patch_size")) + + return kwargs + + def _validate_preprocess_kwargs(self, **kwargs): + """ + Skip standard validation as Pix2Struct uses custom preprocessing. + """ + # Pix2Struct doesn't use standard resize/rescale/normalize parameters + # so we skip the default validation + pass + + def render_header( + self, + image: torch.Tensor, + header: str, + font_bytes: bytes | None = None, + font_path: str | None = None, + ) -> torch.Tensor: + """ + Render header text on image using torch tensors. + + Args: + image (`torch.Tensor`): + Image tensor in channel-first format (C, H, W). + header (`str`): + Header text to render. + font_bytes (`bytes`, *optional*): + Font bytes to use for rendering. + font_path (`str`, *optional*): + Path to font file to use for rendering. + + Returns: + `torch.Tensor`: Image with header in channel-first format (C, H, W). + """ + device = image.device + dtype = image.dtype + + # Convert tensor to PIL (channel-first to channel-last for PIL) + if image.dtype == torch.uint8: + image_pil = tvF.to_pil_image(image) + else: + # If float, convert to uint8 first + image_uint8 = (image * 255).clamp(0, 255).to(torch.uint8) + image_pil = tvF.to_pil_image(image_uint8) + + # Render header text as PIL image + header_image = render_text(header, font_bytes=font_bytes, font_path=font_path) + + # Calculate new dimensions + new_width = max(header_image.width, image_pil.width) + new_height = int(image_pil.height * (new_width / image_pil.width)) + new_header_height = int(header_image.height * (new_width / header_image.width)) + + # Create new image and paste header and original image + new_image = Image.new("RGB", (new_width, new_height + new_header_height), "white") + new_image.paste(header_image.resize((new_width, new_header_height)), (0, 0)) + new_image.paste(image_pil.resize((new_width, new_height)), (0, new_header_height)) + + # Convert back to tensor (channel-first) + result = tvF.pil_to_tensor(new_image).to(device) + + # Convert back to original dtype if needed + if dtype != torch.uint8: + result = result.float() / 255.0 + + return result + + def normalize(self, images: torch.Tensor) -> torch.Tensor: + """ + Normalize batched images using per-image mean and standard deviation. + + Args: + images (`torch.Tensor`): + Batched float image tensor of shape (B, C, H, W). + + Returns: + `torch.Tensor`: Normalized images of shape (B, C, H, W). + """ + # Compute mean and std per image along spatial and channel dimensions + mean = images.mean(dim=(1, 2, 3), keepdim=True) # Shape: (B, 1, 1, 1) + std = images.std(dim=(1, 2, 3), keepdim=True) # Shape: (B, 1, 1, 1) + + num_elements_per_image = images.shape[1] * images.shape[2] * images.shape[3] + min_std = 1.0 / num_elements_per_image**0.5 + adjusted_stddev = torch.maximum(std, torch.tensor(min_std, device=std.device)) + + return (images - mean) / adjusted_stddev + + def extract_flattened_patches( + self, + images: torch.Tensor, + max_patches: int, + patch_size: SizeDict, + ) -> torch.Tensor: + """ + Extract flattened patches from a batch of images. + + Args: + images (`torch.Tensor`): + Batched images tensor of shape (batch, channels, height, width). + max_patches (`int`): + Maximum number of patches to extract. + patch_size (`dict[str, int]`): + Dictionary containing patch height and width. + + Returns: + `torch.Tensor`: Batched flattened patches with row/column IDs of shape (batch, max_patches, patch_dim). + """ + patch_height, patch_width = patch_size.height, patch_size.width + batch_size, channels, image_height, image_width = images.shape + + # Calculate scale to maximize patches while respecting max_patches + scale = (max_patches * (patch_height / image_height) * (patch_width / image_width)) ** 0.5 + num_feasible_rows = max(min(int(scale * image_height / patch_height), max_patches), 1) + num_feasible_cols = max(min(int(scale * image_width / patch_width), max_patches), 1) + resized_height = max(num_feasible_rows * patch_height, 1) + resized_width = max(num_feasible_cols * patch_width, 1) + + # Resize images (batched) using parent class method + resize_size = SizeDict(height=resized_height, width=resized_width) + images = self.resize( + image=images, size=resize_size, interpolation=tvF.InterpolationMode.BILINEAR, antialias=True + ) + + # Extract patches: [batch, rows, columns, patch_height * patch_width * channels] + patches = torch_extract_patches(images, patch_height, patch_width) + + batch_size, rows, columns, depth = patches.shape + + # Reshape to [batch, rows * columns, depth] + patches = patches.reshape(batch_size, rows * columns, depth) + + # Create row and column IDs + row_ids = ( + torch.arange(rows, device=images.device).reshape(rows, 1).repeat(1, columns).reshape(1, rows * columns, 1) + ) + col_ids = ( + torch.arange(columns, device=images.device) + .reshape(1, columns) + .repeat(rows, 1) + .reshape(1, rows * columns, 1) + ) + + # Expand to batch size + row_ids = row_ids.expand(batch_size, -1, -1) + col_ids = col_ids.expand(batch_size, -1, -1) + + # Offset by 1 so IDs don't contain zeros (which represent padding) + row_ids = (row_ids + 1).float() + col_ids = (col_ids + 1).float() + + # Concatenate row_ids, col_ids, and patches: [batch, rows * columns, 2 + depth] + result = torch.cat([row_ids, col_ids, patches], dim=-1) + + # Pad to max_patches: [batch, max_patches, 2 + depth] + result = torch.nn.functional.pad(result, [0, 0, 0, max_patches - (rows * columns)]).float() + + return result + + @auto_docstring + def preprocess( + self, + images: ImageInput, + header_text: str | list[str] | None = None, + **kwargs: Unpack[Pix2StructImageProcessorKwargs], + ) -> BatchFeature: + r""" + header_text (`Union[str, list[str]]`, *optional*): + Text to render as a header. Only has an effect if `image_processor.is_vqa` is `True`. + """ + return super().preprocess(images, header_text=header_text, **kwargs) + + def _preprocess_image_like_inputs( + self, + images: ImageInput, + header_text: str | list[str] | None = None, + do_convert_rgb: bool = True, + input_data_format: ChannelDimension = ChannelDimension.FIRST, + device: str | torch.device | None = None, + **kwargs: Unpack[Pix2StructImageProcessorKwargs], + ) -> BatchFeature: + """ + Preprocess images for Pix2Struct. + """ + # Prepare images (converts to torch tensors) + images = self._prepare_image_like_inputs( + images=images, + do_convert_rgb=do_convert_rgb, + input_data_format=input_data_format, + device=device, + ) + + # Handle VQA mode with header rendering + is_vqa = kwargs.get("is_vqa", self.is_vqa) + if is_vqa: + if header_text is None: + raise ValueError("A header text must be provided for VQA models.") + + font_bytes = kwargs.pop("font_bytes", None) + font_path = kwargs.pop("font_path", None) + + if isinstance(header_text, str): + header_text = [header_text] * len(images) + + # Render headers using torch-native method + images = [ + self.render_header(image, header_text[i], font_bytes=font_bytes, font_path=font_path) + for i, image in enumerate(images) + ] + + return self._preprocess(images, **kwargs) + + def _preprocess( + self, + images: list[torch.Tensor], + do_normalize: bool, + max_patches: int, + patch_size: SizeDict, + return_tensors: str | TensorType | None, + disable_grouping: bool, + **kwargs, + ) -> BatchFeature: + """ + Preprocess images to extract flattened patches. + """ + # Group images by shape first for efficient batch processing + grouped_images, grouped_images_index = group_images_by_shape(images, disable_grouping=disable_grouping) + + flattened_patches_grouped = {} + attention_masks_grouped = {} + + for shape, stacked_images in grouped_images.items(): + # Convert to float if needed (for resize and other operations) + if stacked_images.dtype == torch.uint8: + stacked_images = stacked_images.float() + + # Normalize batched images with per-image mean and std + if do_normalize: + stacked_images = self.normalize(stacked_images) + + patches = self.extract_flattened_patches( + images=stacked_images, max_patches=max_patches, patch_size=patch_size + ) + masks = (patches.sum(dim=-1) != 0).float() + + flattened_patches_grouped[shape] = patches + attention_masks_grouped[shape] = masks + + flattened_patches = reorder_images(flattened_patches_grouped, grouped_images_index) + attention_masks = reorder_images(attention_masks_grouped, grouped_images_index) + + # Stack if return_tensors is set + if return_tensors: + flattened_patches = torch.stack(flattened_patches, dim=0) + attention_masks = torch.stack(attention_masks, dim=0) + + return BatchFeature( + data={"flattened_patches": flattened_patches, "attention_mask": attention_masks}, + tensor_type=return_tensors, + ) + + +__all__ = ["Pix2StructImageProcessorFast"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pix2struct/modeling_pix2struct.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pix2struct/modeling_pix2struct.py new file mode 100644 index 0000000000000000000000000000000000000000..5e6d3c97919cb83c2375d194f16227e874a0eaf1 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pix2struct/modeling_pix2struct.py @@ -0,0 +1,1384 @@ +# Copyright 2023 The HuggingFace Inc. & Google team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""Pix2Struct modeling file""" + +import math + +import torch +from torch import nn + +from ... import initialization as init +from ...activations import ACT2FN +from ...cache_utils import Cache, DynamicCache, EncoderDecoderCache +from ...generation import GenerationMixin +from ...masking_utils import create_causal_mask +from ...modeling_layers import GradientCheckpointingLayer +from ...modeling_outputs import ( + BaseModelOutput, + BaseModelOutputWithPooling, + CausalLMOutputWithCrossAttentions, + Seq2SeqLMOutput, + Seq2SeqModelOutput, +) +from ...modeling_utils import PreTrainedModel +from ...utils import ( + DUMMY_INPUTS, + DUMMY_MASK, + auto_docstring, + is_torchdynamo_compiling, + logging, +) +from .configuration_pix2struct import Pix2StructConfig, Pix2StructTextConfig, Pix2StructVisionConfig + + +logger = logging.get_logger(__name__) + +# General docstring + + +# Adapted from transformers.models.t5.modeling_t5.T5LayerNorm with T5->Pix2Struct +class Pix2StructLayerNorm(nn.Module): + def __init__(self, hidden_size, eps=1e-6): + """ + Construct a layernorm module in the T5 style. No bias and no subtraction of mean. + """ + super().__init__() + self.weight = nn.Parameter(torch.ones(hidden_size)) + self.variance_epsilon = eps + + def forward(self, hidden_states): + # T5 uses a layer_norm which only scales and doesn't shift, which is also known as Root Mean + # Square Layer Normalization https://huggingface.co/papers/1910.07467 thus variance is calculated + # w/o mean and there is no bias. Additionally we want to make sure that the accumulation for + # half-precision inputs is done in fp32 + + variance = hidden_states.to(torch.float32).pow(2).mean(-1, keepdim=True) + hidden_states = hidden_states * torch.rsqrt(variance + self.variance_epsilon) + + # convert into half-precision if necessary + if self.weight.dtype in [torch.float16, torch.bfloat16]: + hidden_states = hidden_states.to(self.weight.dtype) + + return self.weight * hidden_states + + +try: + from apex.normalization import FusedRMSNorm + + Pix2StructLayerNorm = FusedRMSNorm + + logger.info("Discovered apex.normalization.FusedRMSNorm - will use it instead of Pix2StructLayerNorm") +except ImportError: + # using the normal Pix2StructLayerNorm + pass +except Exception: + logger.warning("Discovered apex but it failed to load, falling back to Pix2StructLayerNorm") + + +class Pix2StructVisionEmbeddings(nn.Module): + r""" + Construct the embeddings from patch. In `Pix2Struct` the input is different from classic Vision-transformer models. + Here the input is a sequence of `seq_len` flattened patches that also combines padding patches (tokens). Each patch + is represented by a vector of `hidden_size` values. + """ + + def __init__(self, config: Pix2StructConfig) -> None: + super().__init__() + self.patch_projection = nn.Linear(config.patch_embed_hidden_size, config.hidden_size) + + self.row_embedder = nn.Embedding(config.seq_len, config.hidden_size) + self.column_embedder = nn.Embedding(config.seq_len, config.hidden_size) + + self.dropout = nn.Dropout(config.dropout_rate) + + def forward(self, flattened_patches: torch.Tensor) -> torch.Tensor: + # the row and column indices are stored in the first and second position of the flattened_patches + # flattened_patches: `batch_size`, `seq_len`, `hidden_size` + 2 + row_indices = flattened_patches[:, :, 0].long() + col_indices = flattened_patches[:, :, 1].long() + + flattened_patches = flattened_patches[:, :, 2:] + + embeddings = self.patch_projection(flattened_patches) + row_embeddings = self.row_embedder(row_indices) + col_embeddings = self.column_embedder(col_indices) + + # sum all embeddings together + embeddings = embeddings + row_embeddings + col_embeddings + + embeddings = self.dropout(embeddings) + + return embeddings + + +class Pix2StructVisionAttention(nn.Module): + def __init__(self, config): + super().__init__() + self.hidden_size = config.hidden_size + self.key_value_proj_dim = config.d_kv + self.n_heads = config.num_attention_heads + self.dropout = config.attention_dropout + self.inner_dim = self.n_heads * self.key_value_proj_dim + + self.query = nn.Linear(self.hidden_size, self.inner_dim, bias=False) + self.key = nn.Linear(self.hidden_size, self.inner_dim, bias=False) + self.value = nn.Linear(self.hidden_size, self.inner_dim, bias=False) + self.output = nn.Linear(self.inner_dim, self.hidden_size, bias=False) + + self.gradient_checkpointing = False + + def forward( + self, + hidden_states, + attention_mask=None, + position_bias=None, + output_attentions=False, + ): + """ + Self-attention block + """ + # Input is (batch_size, seq_length, dim) + # Mask is (batch_size, key_length) (non-causal) or (batch_size, key_length, key_length) + batch_size, seq_length = hidden_states.shape[:2] + + def to_projection_shape(states): + """projection""" + return states.contiguous().view(batch_size, -1, self.n_heads, self.key_value_proj_dim).transpose(1, 2) + + # get query states + # (batch_size, n_heads, seq_length, dim_per_head) + query_states = to_projection_shape(self.query(hidden_states)) + + # get key/value states + key_states = to_projection_shape(self.key(hidden_states)) + value_states = to_projection_shape(self.value(hidden_states)) + + # compute scores + # equivalent of torch.einsum("bnqd,bnkd->bnqk", query_states, key_states), compatible with onnx op>9 + scores = torch.matmul(query_states, key_states.transpose(3, 2)) + + if position_bias is None: + position_bias = torch.zeros( + (1, self.n_heads, seq_length, seq_length), device=scores.device, dtype=scores.dtype + ) + if self.gradient_checkpointing and self.training: + position_bias.requires_grad = True + + if attention_mask.dim() == 2: + position_bias = position_bias + attention_mask[:, None, None, :].to(position_bias.device) + elif attention_mask is not None: + # (batch_size, n_heads, seq_length, key_length) + position_bias = position_bias + attention_mask.to(position_bias.device) + elif not is_torchdynamo_compiling(): + attention_mask = torch.ones( + (batch_size, seq_length), device=position_bias.device, dtype=position_bias.dtype + ) + position_bias = position_bias + attention_mask.to(position_bias.device) + + position_bias = 1 - position_bias + + position_bias_masked = position_bias.masked_fill(position_bias == 1, torch.finfo(scores.dtype).min) + scores += position_bias_masked + scores = torch.max(scores, torch.tensor(torch.finfo(scores.dtype).min)) + + # (batch_size, n_heads, seq_length, key_length) + attn_weights = nn.functional.softmax(scores, dim=-1, dtype=torch.float32).type_as(scores) + + # (batch_size, n_heads, seq_length, key_length) + attn_weights = nn.functional.dropout(attn_weights, p=self.dropout, training=self.training) + + attn_output = torch.matmul(attn_weights, value_states) + + # (batch_size, seq_length, dim) + attn_output = attn_output.transpose(1, 2).contiguous().view(batch_size, -1, self.inner_dim) + + attn_output = self.output(attn_output) + + outputs = (attn_output,) + (position_bias,) + + if output_attentions: + outputs = outputs + (attn_weights,) + return outputs + + +# Copied from transformers.models.t5.modeling_t5.T5DenseGatedActDense with T5DenseGatedActDense->Pix2StructVisionMlp,T5Config->Pix2StructVisionConfig,config.d_model->config.hidden_size,dropout_rate->dropout_rate +class Pix2StructVisionMlp(nn.Module): + def __init__(self, config: Pix2StructVisionConfig): + super().__init__() + self.wi_0 = nn.Linear(config.hidden_size, config.d_ff, bias=False) + self.wi_1 = nn.Linear(config.hidden_size, config.d_ff, bias=False) + self.wo = nn.Linear(config.d_ff, config.hidden_size, bias=False) + self.dropout = nn.Dropout(config.dropout_rate) + self.act = ACT2FN[config.dense_act_fn] + + def forward(self, hidden_states): + hidden_gelu = self.act(self.wi_0(hidden_states)) + hidden_linear = self.wi_1(hidden_states) + hidden_states = hidden_gelu * hidden_linear + hidden_states = self.dropout(hidden_states) + + # To make 8bit quantization work for google/flan-t5-xxl, self.wo is kept in float32. + # See https://github.com/huggingface/transformers/issues/20287 + # we also make sure the weights are not in `int8` in case users will force `_keep_in_fp32_modules` to be `None`` + if ( + isinstance(self.wo.weight, torch.Tensor) + and hidden_states.dtype != self.wo.weight.dtype + and self.wo.weight.dtype != torch.int8 + ): + hidden_states = hidden_states.to(self.wo.weight.dtype) + + hidden_states = self.wo(hidden_states) + return hidden_states + + +class Pix2StructVisionLayer(GradientCheckpointingLayer): + def __init__(self, config: Pix2StructConfig) -> None: + super().__init__() + self.chunk_size_feed_forward = config.chunk_size_feed_forward + self.seq_len_dim = 1 + self.attention = Pix2StructVisionAttention(config) + self.mlp = Pix2StructVisionMlp(config) + self.pre_mlp_layer_norm = Pix2StructLayerNorm(config.hidden_size, eps=config.layer_norm_eps) + self.pre_attention_layer_norm = Pix2StructLayerNorm(config.hidden_size, eps=config.layer_norm_eps) + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.Tensor | None = None, + output_attentions: bool = False, + ) -> tuple[torch.Tensor, torch.Tensor] | tuple[torch.Tensor]: + residual = hidden_states + + # in Pix2StructVision, layernorm is applied before self-attention + hidden_states = self.pre_attention_layer_norm(hidden_states) + + self_attention_outputs = self.attention( + hidden_states, + attention_mask=attention_mask, + output_attentions=output_attentions, + ) + attention_output = self_attention_outputs[0] + outputs = self_attention_outputs[1:] # add self attentions if we output attention weights + + # first residual connection + hidden_states = attention_output + residual + + # in Pix2StructVision, layernorm is also applied after self-attention + layer_output = self.pre_mlp_layer_norm(hidden_states) + layer_output = self.mlp(layer_output) + hidden_states # second residual connection + + outputs = (layer_output,) + outputs + + return outputs + + +class Pix2StructVisionEncoder(nn.Module): + def __init__(self, config: Pix2StructVisionConfig) -> None: + super().__init__() + self.config = config + self.layer = nn.ModuleList([Pix2StructVisionLayer(config) for _ in range(config.num_hidden_layers)]) + self.gradient_checkpointing = False + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.Tensor | None = None, + output_attentions: bool = False, + output_hidden_states: bool = False, + return_dict: bool = True, + ) -> tuple | BaseModelOutput: + all_hidden_states = () if output_hidden_states else None + all_self_attentions = () if output_attentions else None + + for i, layer_module in enumerate(self.layer): + if output_hidden_states: + all_hidden_states = all_hidden_states + (hidden_states,) + + layer_outputs = layer_module(hidden_states, attention_mask, output_attentions) + + hidden_states = layer_outputs[0] + + if output_attentions: + all_self_attentions = all_self_attentions + (layer_outputs[1],) + + if output_hidden_states: + all_hidden_states = all_hidden_states + (hidden_states,) + + if not return_dict: + return tuple(v for v in [hidden_states, all_hidden_states, all_self_attentions] if v is not None) + return BaseModelOutput( + last_hidden_state=hidden_states, + hidden_states=all_hidden_states, + attentions=all_self_attentions, + ) + + +@auto_docstring +class Pix2StructPreTrainedModel(PreTrainedModel): + config: Pix2StructConfig + input_modalities = ("image", "text") + + _can_compile_fullgraph = False + + @property + def dummy_inputs(self): + input_ids = torch.tensor(DUMMY_INPUTS) + input_mask = torch.tensor(DUMMY_MASK) + dummy_inputs = { + "decoder_input_ids": input_ids, + "input_ids": input_ids, + "decoder_attention_mask": input_mask, + } + return dummy_inputs + + @torch.no_grad() + def _init_weights(self, module): + """Initialize the weights""" + factor = self.config.initializer_factor # Used for testing weights initialization + if isinstance(module, Pix2StructLayerNorm): + init.constant_(module.weight, factor * 1.0) + elif isinstance(module, Pix2StructTextDenseGatedActDense): + hidden_size = ( + self.config.text_config.hidden_size + if isinstance(self.config, Pix2StructConfig) + else self.config.hidden_size + ) + d_ff = self.config.text_config.d_ff if isinstance(self.config, Pix2StructConfig) else self.config.d_ff + + init.normal_(module.wi_0.weight, mean=0.0, std=factor * ((hidden_size) ** -0.5)) + if hasattr(module.wi_0, "bias") and module.wi_0.bias is not None: + init.zeros_(module.wi_0.bias) + init.normal_(module.wi_1.weight, mean=0.0, std=factor * ((hidden_size) ** -0.5)) + if hasattr(module.wi_1, "bias") and module.wi_1.bias is not None: + init.zeros_(module.wi_1.bias) + init.normal_(module.wo.weight, mean=0.0, std=factor * ((d_ff) ** -0.5)) + if hasattr(module.wo, "bias") and module.wo.bias is not None: + init.zeros_(module.wo.bias) + elif isinstance(module, Pix2StructTextAttention): + hidden_size = ( + self.config.text_config.hidden_size + if isinstance(self.config, Pix2StructConfig) + else self.config.hidden_size + ) + key_value_proj_dim = ( + self.config.text_config.d_kv if isinstance(self.config, Pix2StructConfig) else self.config.hidden_size + ) + n_heads = ( + self.config.text_config.num_heads + if isinstance(self.config, Pix2StructConfig) + else self.config.num_heads + ) + + init.normal_(module.query.weight, mean=0.0, std=factor * ((hidden_size * key_value_proj_dim) ** -0.5)) + init.normal_(module.key.weight, mean=0.0, std=factor * (hidden_size**-0.5)) + init.normal_(module.value.weight, mean=0.0, std=factor * (hidden_size**-0.5)) + init.normal_(module.output.weight, mean=0.0, std=factor * ((n_heads * key_value_proj_dim) ** -0.5)) + if module.has_relative_attention_bias: + init.normal_(module.relative_attention_bias.weight, mean=0.0, std=factor * ((hidden_size) ** -0.5)) + elif isinstance(module, nn.Embedding): + hidden_size = ( + self.config.text_config.hidden_size + if isinstance(self.config, Pix2StructConfig) + else self.config.hidden_size + ) + + init.normal_(module.weight, mean=0.0, std=factor * ((hidden_size) ** -0.5)) + # Here we need the check explicitly, as we slice the weight in the `zeros_` call, so it looses the flag + if module.padding_idx is not None and not getattr(module.weight, "_is_hf_initialized", False): + init.zeros_(module.weight[module.padding_idx]) + elif isinstance(module, Pix2StructTextModel): + hidden_size = ( + self.config.text_config.hidden_size + if isinstance(self.config, Pix2StructConfig) + else self.config.hidden_size + ) + + init.normal_(module.lm_head.weight, mean=0.0, std=factor * ((hidden_size) ** -0.5)) + elif isinstance(module, (nn.Linear, nn.Conv2d)): + init.trunc_normal_(module.weight, mean=0.0, std=self.config.initializer_range) + if module.bias is not None: + init.zeros_(module.bias) + elif isinstance(module, Pix2StructLayerNorm): + if module.weight is not None: + init.ones_(module.weight) + elif isinstance(module, nn.Embedding): + init.normal_(module.weight, mean=0.0, std=self.config.initializer_range) + # Here we need the check explicitly, as we slice the weight in the `zeros_` call, so it looses the flag + if module.padding_idx is not None and not getattr(module.weight, "_is_hf_initialized", False): + init.zeros_(module.weight[module.padding_idx]) + + # Copied from transformers.models.t5.modeling_t5.T5PreTrainedModel._shift_right with T5->Pix2Struct + def _shift_right(self, input_ids): + decoder_start_token_id = self.config.decoder_start_token_id + pad_token_id = self.config.pad_token_id + + if decoder_start_token_id is None: + raise ValueError( + "self.model.config.decoder_start_token_id has to be defined. In Pix2Struct it is usually set to the pad_token_id. " + "See Pix2Struct docs for more information." + ) + + shifted_input_ids = input_ids.new_zeros(input_ids.shape) + shifted_input_ids[..., 1:] = input_ids[..., :-1].clone() + shifted_input_ids[..., 0] = decoder_start_token_id + + if pad_token_id is None: + raise ValueError("self.model.config.pad_token_id has to be defined.") + # replace possible -100 values in labels by `pad_token_id` + shifted_input_ids.masked_fill_(shifted_input_ids == -100, pad_token_id) + + return shifted_input_ids + + +@auto_docstring +class Pix2StructVisionModel(Pix2StructPreTrainedModel): + config: Pix2StructVisionConfig + main_input_name = "flattened_patches" + input_modalities = ("image",) + supports_gradient_checkpointing = True + _no_split_modules = ["Pix2StructVisionLayer"] + + def __init__(self, config: Pix2StructVisionConfig): + super().__init__(config) + self.config = config + + self.embeddings = Pix2StructVisionEmbeddings(config) + self.encoder = Pix2StructVisionEncoder(config) + + self.layernorm = Pix2StructLayerNorm(config.hidden_size, eps=config.layer_norm_eps) + + # Initialize weights and apply final processing + self.post_init() + + def get_input_embeddings(self): + return self.embeddings.patch_projection + + @auto_docstring + def forward( + self, + flattened_patches: torch.Tensor | None = None, + attention_mask: torch.Tensor | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + **kwargs, + ) -> tuple | BaseModelOutputWithPooling: + r""" + flattened_patches (`torch.FloatTensor` of shape `(batch_size, sequence_length, num_channels x patch_height x patch_width)`): + Flattened and padded pixel values. These values can be obtained using [`AutoImageProcessor`]. See + [`Pix2StructVisionImageProcessor.__call__`] for details. Check the [original + paper](https://huggingface.co/papers/2210.03347) (figure 5) for more details. + + Example: + + ```python + >>> import httpx + >>> from io import BytesIO + >>> from PIL import Image + >>> from transformers import AutoProcessor, Pix2StructVisionModel + + >>> image_processor = AutoProcessor.from_pretrained("google/pix2struct-textcaps-base") + >>> model = Pix2StructVisionModel.from_pretrained("google/pix2struct-textcaps-base") + + >>> url = "https://www.ilankelman.org/stopsigns/australia.jpg" + >>> with httpx.stream("GET", url) as response: + ... image = Image.open(BytesIO(response.read())) + + >>> inputs = image_processor(images=image, return_tensors="pt") + >>> with torch.no_grad(): + ... outputs = model(**inputs) + + >>> last_hidden_states = outputs.last_hidden_state + >>> list(last_hidden_states.shape) + [1, 2048, 768] + ``` + """ + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + if flattened_patches is None: + raise ValueError("You have to specify flattened_patches") + + if attention_mask is None: + # check where `flattened_patches` is not 0 + attention_mask = (flattened_patches.sum(dim=-1) != 0).float() + + embedding_output = self.embeddings(flattened_patches) + + encoder_outputs = self.encoder( + embedding_output, + attention_mask=attention_mask, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + sequence_output = encoder_outputs[0] + sequence_output = self.layernorm(sequence_output) + + if not return_dict: + head_outputs = (sequence_output,) + return head_outputs + encoder_outputs[1:] + + return BaseModelOutput( + last_hidden_state=sequence_output, + hidden_states=encoder_outputs.hidden_states, + attentions=encoder_outputs.attentions, + ) + + +# Copied from transformers.models.t5.modeling_t5.T5DenseGatedActDense with T5->Pix2StructText,d_model->hidden_size +class Pix2StructTextDenseGatedActDense(nn.Module): + def __init__(self, config: Pix2StructTextConfig): + super().__init__() + self.wi_0 = nn.Linear(config.hidden_size, config.d_ff, bias=False) + self.wi_1 = nn.Linear(config.hidden_size, config.d_ff, bias=False) + self.wo = nn.Linear(config.d_ff, config.hidden_size, bias=False) + self.dropout = nn.Dropout(config.dropout_rate) + self.act = ACT2FN[config.dense_act_fn] + + def forward(self, hidden_states): + hidden_gelu = self.act(self.wi_0(hidden_states)) + hidden_linear = self.wi_1(hidden_states) + hidden_states = hidden_gelu * hidden_linear + hidden_states = self.dropout(hidden_states) + + # To make 8bit quantization work for google/flan-t5-xxl, self.wo is kept in float32. + # See https://github.com/huggingface/transformers/issues/20287 + # we also make sure the weights are not in `int8` in case users will force `_keep_in_fp32_modules` to be `None`` + if ( + isinstance(self.wo.weight, torch.Tensor) + and hidden_states.dtype != self.wo.weight.dtype + and self.wo.weight.dtype != torch.int8 + ): + hidden_states = hidden_states.to(self.wo.weight.dtype) + + hidden_states = self.wo(hidden_states) + return hidden_states + + +class Pix2StructTextLayerFF(nn.Module): + def __init__(self, config: Pix2StructTextConfig): + super().__init__() + self.DenseReluDense = Pix2StructTextDenseGatedActDense(config) + + self.layer_norm = Pix2StructLayerNorm(config.hidden_size, eps=config.layer_norm_epsilon) + self.dropout = nn.Dropout(config.dropout_rate) + + # Copied from transformers.models.t5.modeling_t5.T5LayerFF.forward + def forward(self, hidden_states): + forwarded_states = self.layer_norm(hidden_states) + forwarded_states = self.DenseReluDense(forwarded_states) + hidden_states = hidden_states + self.dropout(forwarded_states) + return hidden_states + + +class Pix2StructTextAttention(nn.Module): + def __init__(self, config: Pix2StructTextConfig, has_relative_attention_bias=False, layer_idx: int | None = None): + super().__init__() + self.has_relative_attention_bias = has_relative_attention_bias + self.relative_attention_num_buckets = config.relative_attention_num_buckets + self.relative_attention_max_distance = config.relative_attention_max_distance + self.hidden_size = config.hidden_size + self.key_value_proj_dim = config.d_kv + self.n_heads = config.num_heads + self.dropout = config.dropout_rate + self.inner_dim = self.n_heads * self.key_value_proj_dim + self.layer_idx = layer_idx + if layer_idx is None: + logger.warning_once( + f"Instantiating a decoder {self.__class__.__name__} without passing `layer_idx` is not recommended and " + "will to errors during the forward call, if caching is used. Please make sure to provide a `layer_idx` " + "when creating this class." + ) + + self.query = nn.Linear(self.hidden_size, self.hidden_size, bias=False) + self.key = nn.Linear(self.hidden_size, self.hidden_size, bias=False) + self.value = nn.Linear(self.hidden_size, self.hidden_size, bias=False) + self.output = nn.Linear(self.hidden_size, self.hidden_size, bias=False) + + if self.has_relative_attention_bias: + self.relative_attention_bias = nn.Embedding(self.relative_attention_num_buckets, self.n_heads) + + self.gradient_checkpointing = False + + @staticmethod + # Copied from transformers.models.t5.modeling_t5.T5Attention._relative_position_bucket + def _relative_position_bucket(relative_position, bidirectional=True, num_buckets=32, max_distance=128): + """ + Adapted from Mesh Tensorflow: + https://github.com/tensorflow/mesh/blob/0cb87fe07da627bf0b7e60475d59f95ed6b5be3d/mesh_tensorflow/transformer/transformer_layers.py#L593 + + Translate relative position to a bucket number for relative attention. The relative position is defined as + memory_position - query_position, i.e. the distance in tokens from the attending position to the attended-to + position. If bidirectional=False, then positive relative positions are invalid. We use smaller buckets for + small absolute relative_position and larger buckets for larger absolute relative_positions. All relative + positions >=max_distance map to the same bucket. All relative positions <=-max_distance map to the same bucket. + This should allow for more graceful generalization to longer sequences than the model has been trained on + + Args: + relative_position: an int32 Tensor + bidirectional: a boolean - whether the attention is bidirectional + num_buckets: an integer + max_distance: an integer + + Returns: + a Tensor with the same shape as relative_position, containing int32 values in the range [0, num_buckets) + """ + relative_buckets = 0 + if bidirectional: + num_buckets //= 2 + relative_buckets += (relative_position > 0).to(torch.long) * num_buckets + relative_position = torch.abs(relative_position) + else: + relative_position = -torch.min(relative_position, torch.zeros_like(relative_position)) + # now relative_position is in the range [0, inf) + + # half of the buckets are for exact increments in positions + max_exact = num_buckets // 2 + is_small = relative_position < max_exact + + # The other half of the buckets are for logarithmically bigger bins in positions up to max_distance + relative_position_if_large = max_exact + ( + torch.log(relative_position.float() / max_exact) + / math.log(max_distance / max_exact) + * (num_buckets - max_exact) + ).to(torch.long) + relative_position_if_large = torch.min( + relative_position_if_large, torch.full_like(relative_position_if_large, num_buckets - 1) + ) + + relative_buckets += torch.where(is_small, relative_position, relative_position_if_large) + return relative_buckets + + # Adapted from transformers.models.t5.modeling_t5.T5Attention.compute_bias + def compute_bias(self, query_length, key_length, device=None, cache_position=None): + """Compute binned relative position bias""" + if device is None: + device = self.relative_attention_bias.weight.device + if cache_position is None: + context_position = torch.arange(query_length, dtype=torch.long, device=device)[:, None] + else: + context_position = cache_position[:, None].to(device) + memory_position = torch.arange(key_length, dtype=torch.long, device=device)[None, :] + relative_position = memory_position - context_position # shape (query_length, key_length) + relative_position_bucket = self._relative_position_bucket( + relative_position, # shape (query_length, key_length) + bidirectional=False, + num_buckets=self.relative_attention_num_buckets, + max_distance=self.relative_attention_max_distance, + ) + values = self.relative_attention_bias(relative_position_bucket) # shape (query_length, key_length, num_heads) + values = values.permute([2, 0, 1]).unsqueeze(0) # shape (1, num_heads, query_length, key_length) + return values + + # Adapted from transformers.models.t5.modeling_t5.T5Attention.forward + def forward( + self, + hidden_states, + mask=None, + key_value_states=None, + position_bias=None, + past_key_values=None, + query_length=None, + use_cache=False, + output_attentions=False, + cache_position=None, + ): + """ + Self-attention (if key_value_states is None) or attention over source sentence (provided by key_value_states). + """ + # Input is (batch_size, seq_length, dim) + # Mask is (batch_size, 1, 1, key_length) (non-causal) or (batch_size, 1, seq_length, key_length) (causal decoder) + batch_size, seq_length = hidden_states.shape[:2] + + # if key_value_states are provided this layer is used as a cross-attention layer for the decoder + is_cross_attention = key_value_states is not None + + query_states = self.query(hidden_states) + query_states = query_states.view(batch_size, -1, self.n_heads, self.key_value_proj_dim).transpose(1, 2) + + # Check is encoder-decoder model is being used. Otherwise we'll get `DynamicCache` + if past_key_values is not None and isinstance(past_key_values, EncoderDecoderCache): + is_updated = past_key_values.is_updated.get(self.layer_idx) + if is_cross_attention: + # after the first generated id, we can subsequently re-use all key/value_states from cache + curr_past_key_values = past_key_values.cross_attention_cache + else: + curr_past_key_values = past_key_values.self_attention_cache + else: + curr_past_key_values = past_key_values + + current_states = key_value_states if is_cross_attention else hidden_states + if is_cross_attention and past_key_values and is_updated: + # reuse k,v, cross_attentions + key_states = curr_past_key_values.layers[self.layer_idx].keys + value_states = curr_past_key_values.layers[self.layer_idx].values + else: + key_states = self.key(current_states) + value_states = self.value(current_states) + key_states = key_states.view(batch_size, -1, self.n_heads, self.key_value_proj_dim).transpose(1, 2) + value_states = value_states.view(batch_size, -1, self.n_heads, self.key_value_proj_dim).transpose(1, 2) + + if past_key_values is not None: + # save all key/value_states to cache to be re-used for fast auto-regressive generation + cache_position = cache_position if not is_cross_attention else None + key_states, value_states = curr_past_key_values.update( + key_states, value_states, self.layer_idx, {"cache_position": cache_position} + ) + # set flag that curr layer for cross-attn is already updated so we can re-use in subsequent calls + if is_cross_attention: + past_key_values.is_updated[self.layer_idx] = True + + # compute scores, equivalent of torch.einsum("bnqd,bnkd->bnqk", query_states, key_states), compatible with onnx op>9 + scores = torch.matmul(query_states, key_states.transpose(3, 2)) + + if position_bias is None: + key_length = key_states.shape[-2] + # cache position is 0-indexed so we add 1 to get the real length of queries (aka with past) + real_seq_length = query_length if query_length is not None else cache_position[-1] + 1 + if not self.has_relative_attention_bias: + position_bias = torch.zeros( + (1, self.n_heads, seq_length, key_length), device=scores.device, dtype=scores.dtype + ) + if self.gradient_checkpointing and self.training: + position_bias.requires_grad = True + else: + position_bias = self.compute_bias( + real_seq_length, key_length, device=scores.device, cache_position=cache_position + ) + position_bias = position_bias[:, :, -seq_length:, :] + + if mask is not None: + causal_mask = mask[:, :, :, : key_states.shape[-2]] + position_bias = position_bias + causal_mask + + position_bias_masked = position_bias + scores += position_bias_masked + + # (batch_size, n_heads, seq_length, key_length) + attn_weights = nn.functional.softmax(scores.float(), dim=-1).type_as(scores) + attn_weights = nn.functional.dropout(attn_weights, p=self.dropout, training=self.training) + + attn_output = torch.matmul(attn_weights, value_states) + + attn_output = attn_output.transpose(1, 2).contiguous() + attn_output = attn_output.view(batch_size, -1, self.inner_dim) + attn_output = self.output(attn_output) + + outputs = (attn_output, position_bias) + + if output_attentions: + outputs = outputs + (attn_weights,) + return outputs + + +# Copied from transformers.models.t5.modeling_t5.T5LayerSelfAttention with T5LayerNorm->Pix2StructLayerNorm,T5Attention->Pix2StructTextAttention,T5LayerSelfAttention->Pix2StructTextLayerSelfAttention,self.SelfAttention->self.attention,config.d_model->config.hidden_size +class Pix2StructTextLayerSelfAttention(nn.Module): + def __init__(self, config, has_relative_attention_bias=False, layer_idx: int | None = None): + super().__init__() + self.attention = Pix2StructTextAttention( + config, has_relative_attention_bias=has_relative_attention_bias, layer_idx=layer_idx + ) + self.layer_norm = Pix2StructLayerNorm(config.hidden_size, eps=config.layer_norm_epsilon) + self.dropout = nn.Dropout(config.dropout_rate) + + def forward( + self, + hidden_states, + attention_mask=None, + position_bias=None, + past_key_values=None, + use_cache=False, + output_attentions=False, + cache_position=None, + ): + normed_hidden_states = self.layer_norm(hidden_states) + attention_output = self.attention( + normed_hidden_states, + mask=attention_mask, + position_bias=position_bias, + past_key_values=past_key_values, + use_cache=use_cache, + output_attentions=output_attentions, + cache_position=cache_position, + ) + hidden_states = hidden_states + self.dropout(attention_output[0]) + outputs = (hidden_states,) + attention_output[1:] # add attentions if we output them + return outputs + + +# Copied from transformers.models.t5.modeling_t5.T5LayerCrossAttention with T5LayerNorm->Pix2StructLayerNorm,T5Attention->Pix2StructTextAttention,T5LayerCrossAttention->Pix2StructTextLayerCrossAttention,self.EncDecAttention->self.attention,config.d_model->config.hidden_size +class Pix2StructTextLayerCrossAttention(nn.Module): + def __init__(self, config, layer_idx: int | None = None): + super().__init__() + self.attention = Pix2StructTextAttention(config, has_relative_attention_bias=False, layer_idx=layer_idx) + self.layer_norm = Pix2StructLayerNorm(config.hidden_size, eps=config.layer_norm_epsilon) + self.dropout = nn.Dropout(config.dropout_rate) + + def forward( + self, + hidden_states, + key_value_states, + attention_mask=None, + position_bias=None, + past_key_values=None, + use_cache=False, + query_length=None, + output_attentions=False, + cache_position=None, + ): + normed_hidden_states = self.layer_norm(hidden_states) + attention_output = self.attention( + normed_hidden_states, + mask=attention_mask, + key_value_states=key_value_states, + position_bias=position_bias, + past_key_values=past_key_values, + use_cache=use_cache, + query_length=query_length, + output_attentions=output_attentions, + cache_position=cache_position, + ) + layer_output = hidden_states + self.dropout(attention_output[0]) + outputs = (layer_output,) + attention_output[1:] # add attentions if we output them + return outputs + + +class Pix2StructTextBlock(GradientCheckpointingLayer): + def __init__(self, config, has_relative_attention_bias=False, layer_idx: int | None = None): + super().__init__() + + self.self_attention = Pix2StructTextLayerSelfAttention( + config, + has_relative_attention_bias=has_relative_attention_bias, + layer_idx=layer_idx, + ) + + self.encoder_decoder_attention = Pix2StructTextLayerCrossAttention( + config, + layer_idx=layer_idx, + ) + + self.mlp = Pix2StructTextLayerFF(config) + + def forward( + self, + hidden_states, + attention_mask=None, + position_bias=None, + encoder_hidden_states=None, + encoder_attention_mask=None, + encoder_decoder_position_bias=None, + past_key_values=None, + use_cache=False, + output_attentions=False, + return_dict=True, + cache_position=None, + ): + self_attention_outputs = self.self_attention( + hidden_states, + attention_mask=attention_mask, + position_bias=position_bias, + past_key_values=past_key_values, + use_cache=use_cache, + output_attentions=output_attentions, + cache_position=cache_position, + ) + hidden_states = self_attention_outputs[0] + attention_outputs = self_attention_outputs[1:] # Keep self-attention outputs and relative position weights + + # clamp inf values to enable fp16 training + if hidden_states.dtype == torch.float16 and torch.isinf(hidden_states).any(): + clamp_value = torch.finfo(hidden_states.dtype).max - 1000 + hidden_states = torch.clamp(hidden_states, min=-clamp_value, max=clamp_value) + + do_cross_attention = encoder_hidden_states is not None + if do_cross_attention: + cross_attention_outputs = self.encoder_decoder_attention( + hidden_states, + key_value_states=encoder_hidden_states, + attention_mask=encoder_attention_mask, + position_bias=encoder_decoder_position_bias, + past_key_values=past_key_values, + query_length=cache_position[-1] + 1, + use_cache=use_cache, + output_attentions=output_attentions, + ) + hidden_states = cross_attention_outputs[0] + + # clamp inf values to enable fp16 training + if hidden_states.dtype == torch.float16 and torch.isinf(hidden_states).any(): + clamp_value = torch.finfo(hidden_states.dtype).max - 1000 + hidden_states = torch.clamp(hidden_states, min=-clamp_value, max=clamp_value) + + # Keep cross-attention outputs and relative position weights + attention_outputs = attention_outputs + cross_attention_outputs[1:] + + # Apply Feed Forward layer + hidden_states = self.mlp(hidden_states) + + # clamp inf values to enable fp16 training + if hidden_states.dtype == torch.float16 and torch.isinf(hidden_states).any(): + clamp_value = torch.finfo(hidden_states.dtype).max - 1000 + hidden_states = torch.clamp(hidden_states, min=-clamp_value, max=clamp_value) + + outputs = (hidden_states,) + + return outputs + attention_outputs + + +@auto_docstring( + custom_intro=""" + The standalone text decoder of Pix2Struct + """ +) +class Pix2StructTextModel(Pix2StructPreTrainedModel): + config: Pix2StructTextConfig + input_modalities = ("text",) + _no_split_modules = ["Pix2StructTextBlock"] + _tied_weights_keys = {"lm_head.weight": "embed_tokens.weight"} + supports_gradient_checkpointing = True + + def __init__(self, config): + super().__init__(config) + self.embed_tokens = nn.Embedding(config.vocab_size, config.hidden_size) + + self.layer = nn.ModuleList( + [ + Pix2StructTextBlock(config, has_relative_attention_bias=bool(i == 0), layer_idx=i) + for i in range(config.num_layers) + ] + ) + self.final_layer_norm = Pix2StructLayerNorm(config.hidden_size, eps=config.layer_norm_epsilon) + self.dropout = nn.Dropout(config.dropout_rate) + + self.lm_head = nn.Linear(config.hidden_size, config.vocab_size, bias=False) + + # Initialize weights and apply final processing + self.post_init() + self.gradient_checkpointing = False + + def set_input_embeddings(self, new_embeddings): + self.embed_tokens = new_embeddings + + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.FloatTensor | None = None, + encoder_hidden_states: torch.FloatTensor | None = None, + encoder_attention_mask: torch.FloatTensor | None = None, + inputs_embeds: torch.LongTensor | None = None, + past_key_values: Cache | None = None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + labels: torch.LongTensor | None = None, + return_dict: bool | None = None, + cache_position: torch.LongTensor | None = None, + **kwargs, + ) -> tuple[torch.FloatTensor, ...] | CausalLMOutputWithCrossAttentions: + r""" + input_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`): + Indices of input sequence tokens in the vocabulary. Pix2StructText is a model with relative position + embeddings so you should be able to pad the inputs on both the right and the left. + + Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and + [`PreTrainedTokenizer.__call__`] for detail. + + [What are input IDs?](../glossary#input-ids) + + To know more on how to prepare `input_ids` for pretraining take a look a [Pix2StructText + Training](./t5#training). + + Example: + + ```python + >>> from transformers import AutoProcessor, Pix2StructTextModel + + >>> processor = AutoProcessor.from_pretrained("google/pix2struct-textcaps-base") + >>> model = Pix2StructTextModel.from_pretrained("google/pix2struct-textcaps-base") + + >>> inputs = processor(text="Hello, my dog is cute", return_tensors="pt") + >>> outputs = model(**inputs) + >>> loss = outputs.loss + ``` + """ + use_cache = use_cache if use_cache is not None else self.config.use_cache + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + if self.gradient_checkpointing and self.training and use_cache: + logger.warning( + "`use_cache=True` is incompatible with gradient checkpointing. Setting `use_cache=False`..." + ) + use_cache = False + + if input_ids is not None and inputs_embeds is not None: + raise ValueError("You cannot specify both decoder_input_ids and decoder_inputs_embeds at the same time") + elif input_ids is not None: + input_shape = input_ids.size() + input_ids = input_ids.view(-1, input_shape[-1]) + elif inputs_embeds is not None: + input_shape = inputs_embeds.size()[:-1] + else: + raise ValueError("You have to specify either decoder_input_ids or decoder_inputs_embeds") + + if inputs_embeds is None: + assert self.embed_tokens is not None, "You have to initialize the model with valid token embeddings" + inputs_embeds = self.embed_tokens(input_ids) + + batch_size, seq_length = input_shape + + if use_cache and past_key_values is None: + if self.config.is_encoder_decoder: + past_key_values = EncoderDecoderCache( + DynamicCache(config=self.config), DynamicCache(config=self.config) + ) + else: + past_key_values = DynamicCache(config=self.config) + + past_key_values_length = 0 + if cache_position is not None: + past_key_values_length = cache_position[0] + elif past_key_values is not None: + past_key_values_length = past_key_values.get_seq_length() + + if cache_position is None: + cache_position = torch.arange( + past_key_values_length, past_key_values_length + seq_length, device=inputs_embeds.device + ) + + if attention_mask is None: + # required mask seq length can be calculated via length of past + mask_seq_length = ( + past_key_values.get_seq_length() + seq_length if past_key_values is not None else seq_length + ) + attention_mask = torch.ones(batch_size, mask_seq_length, device=inputs_embeds.device) + + if self.config.is_decoder: + causal_mask = create_causal_mask( + config=self.config, + inputs_embeds=inputs_embeds, + attention_mask=attention_mask, + cache_position=cache_position, + past_key_values=past_key_values, + ) + else: + causal_mask = attention_mask[:, None, None, :] + causal_mask = causal_mask.to(dtype=inputs_embeds.dtype) + causal_mask = (1.0 - causal_mask) * torch.finfo(inputs_embeds.dtype).min + + # If a 2D or 3D attention mask is provided for the cross-attention + # we need to make broadcastable to [batch_size, num_heads, seq_length, seq_length] + if encoder_hidden_states is not None: + encoder_batch_size, encoder_sequence_length, _ = encoder_hidden_states.size() + encoder_hidden_shape = (encoder_batch_size, encoder_sequence_length) + if encoder_attention_mask is None: + encoder_attention_mask = torch.ones(encoder_hidden_shape, device=inputs_embeds.device) + encoder_extended_attention_mask = self.invert_attention_mask(encoder_attention_mask) + else: + encoder_extended_attention_mask = None + + all_hidden_states = () if output_hidden_states else None + all_attentions = () if output_attentions else None + all_cross_attentions = () if (output_attentions) else None + position_bias = None + encoder_decoder_position_bias = None + + hidden_states = self.dropout(inputs_embeds) + + for i, layer_module in enumerate(self.layer): + if output_hidden_states: + all_hidden_states = all_hidden_states + (hidden_states,) + + layer_outputs = layer_module( + hidden_states, + causal_mask, + position_bias, + encoder_hidden_states, + encoder_extended_attention_mask, + encoder_decoder_position_bias, # as a positional argument for gradient checkpointing + past_key_values=past_key_values, + use_cache=use_cache, + output_attentions=output_attentions, + cache_position=cache_position, + ) + + hidden_states = layer_outputs[0] + + # We share the position biases between the layers - the first layer store them + # layer_outputs = hidden-states, key-value-states (self-attention position bias), (self-attention weights), + # (cross-attention position bias), (cross-attention weights) + position_bias = layer_outputs[1] + if encoder_hidden_states is not None: + encoder_decoder_position_bias = layer_outputs[3 if output_attentions else 2] + + if output_attentions: + all_attentions = all_attentions + (layer_outputs[2],) + if encoder_hidden_states is not None: + all_cross_attentions = all_cross_attentions + (layer_outputs[4],) + + hidden_states = self.final_layer_norm(hidden_states) + hidden_states = self.dropout(hidden_states) + + logits = self.lm_head(hidden_states) + + # Add last layer + if output_hidden_states: + all_hidden_states = all_hidden_states + (hidden_states,) + + loss = None + if labels is not None: + # move labels to correct device + labels = labels.to(logits.device) + loss_fct = nn.CrossEntropyLoss(ignore_index=-100, reduction="mean") + + loss = loss_fct(logits.contiguous().view(-1, logits.size(-1)), labels.contiguous().view(-1)) + + if not return_dict: + return tuple( + v + for v in [ + loss, + logits, + past_key_values, + all_hidden_states, + all_attentions, + all_cross_attentions, + ] + if v is not None + ) + return CausalLMOutputWithCrossAttentions( + loss=loss, + logits=logits, + past_key_values=past_key_values, + hidden_states=all_hidden_states, + attentions=all_attentions, + cross_attentions=all_cross_attentions, + ) + + +@auto_docstring( + custom_intro=""" + A conditional generation model with a language modeling head. Can be used for sequence generation tasks. + """ +) +class Pix2StructForConditionalGeneration(Pix2StructPreTrainedModel, GenerationMixin): + config: Pix2StructConfig + main_input_name = "flattened_patches" + + def __init__(self, config: Pix2StructConfig): + super().__init__(config) + + self.encoder = Pix2StructVisionModel(config.vision_config) + self.decoder = Pix2StructTextModel(config.text_config) + + self.is_vqa = config.is_vqa + + # Initialize weights and apply final processing + self.post_init() + + def get_input_embeddings(self): + return self.decoder.get_input_embeddings() + + def set_input_embeddings(self, new_embeddings): + self.decoder.set_input_embeddings(new_embeddings) + + def get_output_embeddings(self) -> nn.Module: + return self.decoder.get_output_embeddings() + + def set_output_embeddings(self, new_embeddings): + self.decoder.set_output_embeddings(new_embeddings) + + @auto_docstring + def forward( + self, + flattened_patches: torch.FloatTensor | None = None, + attention_mask: torch.FloatTensor | None = None, + decoder_input_ids: torch.LongTensor | None = None, + decoder_attention_mask: torch.BoolTensor | None = None, + encoder_outputs: tuple[tuple[torch.FloatTensor]] | None = None, + past_key_values: Cache | None = None, + labels: torch.LongTensor | None = None, + decoder_inputs_embeds: torch.Tensor | None = None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + cache_position: torch.LongTensor | None = None, + **kwargs, + ) -> tuple[torch.FloatTensor] | Seq2SeqModelOutput: + r""" + flattened_patches (`torch.FloatTensor` of shape `(batch_size, seq_length, hidden_size)`): + Flattened pixel patches. the `hidden_size` is obtained by the following formula: `hidden_size` = + `num_channels` * `patch_size` * `patch_size` + + The process of flattening the pixel patches is done by `Pix2StructProcessor`. + decoder_input_ids (`torch.LongTensor` of shape `(batch_size, target_sequence_length)`, *optional*): + Indices of decoder input sequence tokens in the vocabulary. + + Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and + [`PreTrainedTokenizer.__call__`] for details. + + [What are decoder input IDs?](../glossary#decoder-input-ids) + + Pix2StructText uses the `pad_token_id` as the starting token for `decoder_input_ids` generation. If + `past_key_values` is used, optionally only the last `decoder_input_ids` have to be input (see + `past_key_values`). + + To know more on how to prepare `decoder_input_ids` for pretraining take a look at [Pix2StructText + Training](./t5#training). + decoder_attention_mask (`torch.BoolTensor` of shape `(batch_size, target_sequence_length)`, *optional*): + Default behavior: generate a tensor that ignores pad tokens in `decoder_input_ids`. Causal mask will also + be used by default. + labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Labels for computing the masked language modeling loss for the decoder. + + Example: + + Inference: + + ```python + >>> from PIL import Image + >>> import httpx + >>> from io import BytesIO + >>> from transformers import AutoProcessor, Pix2StructForConditionalGeneration + + >>> processor = AutoProcessor.from_pretrained("google/pix2struct-textcaps-base") + >>> model = Pix2StructForConditionalGeneration.from_pretrained("google/pix2struct-textcaps-base") + + >>> url = "https://www.ilankelman.org/stopsigns/australia.jpg" + >>> with httpx.stream("GET", url) as response: + ... image = Image.open(BytesIO(response.read())) + + >>> inputs = processor(images=image, return_tensors="pt") + + >>> # autoregressive generation + >>> generated_ids = model.generate(**inputs, max_new_tokens=50) + >>> generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)[0] + >>> print(generated_text) + A stop sign is on a street corner. + + >>> # conditional generation + >>> text = "A picture of" + >>> inputs = processor(text=text, images=image, return_tensors="pt", add_special_tokens=False) + + >>> generated_ids = model.generate(**inputs, max_new_tokens=50) + >>> generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)[0] + >>> print(generated_text) + A picture of a stop sign with a red stop sign + ``` + + Training: + + ```python + >>> from PIL import Image + >>> import httpx + >>> from io import BytesIO + >>> from transformers import AutoProcessor, Pix2StructForConditionalGeneration + + >>> processor = AutoProcessor.from_pretrained("google/pix2struct-base") + >>> model = Pix2StructForConditionalGeneration.from_pretrained("google/pix2struct-base") + + >>> url = "https://www.ilankelman.org/stopsigns/australia.jpg" + >>> with httpx.stream("GET", url) as response: + ... image = Image.open(BytesIO(response.read())) + >>> text = "A stop sign is on the street corner." + + >>> inputs = processor(images=image, return_tensors="pt") + >>> labels = processor(text=text, return_tensors="pt").input_ids + + >>> # forward pass + >>> outputs = model(**inputs, labels=labels) + >>> loss = outputs.loss + >>> print(f"{loss.item():.5f}") + 5.94282 + ```""" + use_cache = use_cache if use_cache is not None else self.config.text_config.use_cache + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + # Encode if needed (training, first prediction pass) + if encoder_outputs is None: + encoder_outputs = self.encoder( + flattened_patches=flattened_patches, + attention_mask=attention_mask, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + elif return_dict and not isinstance(encoder_outputs, BaseModelOutput): + encoder_outputs = BaseModelOutput( + last_hidden_state=encoder_outputs[0], + hidden_states=encoder_outputs[1] if len(encoder_outputs) > 1 else None, + attentions=encoder_outputs[2] if len(encoder_outputs) > 2 else None, + ) + + hidden_states = encoder_outputs[0] + + if labels is not None and decoder_input_ids is None and decoder_inputs_embeds is None: + # get decoder inputs from shifting lm labels to the right + decoder_input_ids = self._shift_right(labels) + decoder_attention_mask = ( + decoder_attention_mask + if decoder_attention_mask is not None + else decoder_input_ids.ne(self.config.pad_token_id).float() + ) + # Always attend to the first token + decoder_attention_mask[:, 0] = 1 + + # Decode + decoder_outputs = self.decoder( + input_ids=decoder_input_ids, + attention_mask=decoder_attention_mask, + inputs_embeds=decoder_inputs_embeds, + past_key_values=past_key_values, + encoder_hidden_states=hidden_states, + encoder_attention_mask=attention_mask, + use_cache=use_cache, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + labels=labels, + return_dict=return_dict, + cache_position=cache_position, + ) + + if not return_dict: + return decoder_outputs + encoder_outputs + + return Seq2SeqLMOutput( + loss=decoder_outputs.loss, + logits=decoder_outputs.logits, + past_key_values=decoder_outputs.past_key_values, + decoder_hidden_states=decoder_outputs.hidden_states, + decoder_attentions=decoder_outputs.attentions, + cross_attentions=decoder_outputs.cross_attentions, + encoder_last_hidden_state=encoder_outputs.last_hidden_state, + encoder_hidden_states=encoder_outputs.hidden_states, + encoder_attentions=encoder_outputs.attentions, + ) + + +__all__ = [ + "Pix2StructPreTrainedModel", + "Pix2StructForConditionalGeneration", + "Pix2StructVisionModel", + "Pix2StructTextModel", +] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pix2struct/processing_pix2struct.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pix2struct/processing_pix2struct.py new file mode 100644 index 0000000000000000000000000000000000000000..189c539daaf0de0fd8e7cda7a099ad689f6a1f1d --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pix2struct/processing_pix2struct.py @@ -0,0 +1,109 @@ +# Copyright 2023 The HuggingFace Inc. team. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +""" +Processor class for Pix2Struct. +""" + +from ...feature_extraction_utils import BatchFeature +from ...processing_utils import ProcessingKwargs, ProcessorMixin, Unpack +from ...tokenization_utils_base import BatchEncoding, PreTokenizedInput, TextInput +from ...utils import auto_docstring, logging + + +class Pix2StructProcessorKwargs(ProcessingKwargs, total=False): + _defaults = { + "text_kwargs": { + "add_special_tokens": True, + "padding": False, + "stride": 0, + "return_overflowing_tokens": False, + "return_special_tokens_mask": False, + "return_offsets_mapping": False, + "return_token_type_ids": False, + "return_length": False, + "verbose": True, + }, + "images_kwargs": { + "max_patches": 2048, + }, + } + + +logger = logging.get_logger(__name__) + + +@auto_docstring +class Pix2StructProcessor(ProcessorMixin): + def __init__(self, image_processor, tokenizer): + tokenizer.return_token_type_ids = False + super().__init__(image_processor, tokenizer) + + @auto_docstring + def __call__( + self, + images=None, + text: TextInput | PreTokenizedInput | list[TextInput] | list[PreTokenizedInput] = None, + **kwargs: Unpack[Pix2StructProcessorKwargs], + ) -> BatchEncoding | BatchFeature: + if images is None and text is None: + raise ValueError("You have to specify either images or text.") + + output_kwargs = self._merge_kwargs( + Pix2StructProcessorKwargs, + tokenizer_init_kwargs=self.tokenizer.init_kwargs, + **kwargs, + ) + add_special_tokens = output_kwargs["text_kwargs"].pop("add_special_tokens", None) + # Get only text + if images is None and not self.image_processor.is_vqa: + output_kwargs["text_kwargs"]["add_special_tokens"] = ( + add_special_tokens if add_special_tokens is not None else True + ) + text_encoding = self.tokenizer(text=text, **output_kwargs["text_kwargs"]) + return text_encoding + + if not self.image_processor.is_vqa: + # add pixel_values + encoding_image_processor = self.image_processor(images, **output_kwargs["images_kwargs"]) + else: + # add pixel_values and bbox + output_kwargs["images_kwargs"].setdefault("header_text", text) + encoding_image_processor = self.image_processor(images, **output_kwargs["images_kwargs"]) + + if text is not None and not self.image_processor.is_vqa: + output_kwargs["text_kwargs"]["add_special_tokens"] = ( + add_special_tokens if add_special_tokens is not None else False + ) + text_encoding = self.tokenizer(text=text, **output_kwargs["text_kwargs"]) + + if "attention_mask" in text_encoding: + text_encoding["decoder_attention_mask"] = text_encoding.pop("attention_mask") + if "input_ids" in text_encoding: + text_encoding["decoder_input_ids"] = text_encoding.pop("input_ids") + else: + text_encoding = None + + if text_encoding is not None: + encoding_image_processor.update(text_encoding) + + return encoding_image_processor + + @property + def model_input_names(self): + image_processor_input_names = self.image_processor.model_input_names + decoder_ids = ["decoder_attention_mask", "decoder_input_ids"] + return image_processor_input_names + decoder_ids + + +__all__ = ["Pix2StructProcessor"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pixio/__init__.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pixio/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..38435cc643c4606d9d118d47c9ec765ecf413d0f --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pixio/__init__.py @@ -0,0 +1,29 @@ +# Copyright 2025 Meta AI and The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""Pixio model configuration""" + +from typing import TYPE_CHECKING + +from ...utils import _LazyModule +from ...utils.import_utils import define_import_structure + + +if TYPE_CHECKING: + from .configuration_pixio import * + from .modeling_pixio import * +else: + import sys + + _file = globals()["__file__"] + sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__) diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pixio/configuration_pixio.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pixio/configuration_pixio.py new file mode 100644 index 0000000000000000000000000000000000000000..7fd5494525863fc340ae221cadca867b9f7eaa6e --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pixio/configuration_pixio.py @@ -0,0 +1,148 @@ +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# This file was automatically generated from src/transformers/models/pixio/modular_pixio.py. +# Do NOT edit this file manually as any edits will be overwritten by the generation of +# the file from the modular. If any change should be done, please apply the change to the +# modular_pixio.py file directly. One of our CI enforces this. +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# Copyright 2025 Meta AI and The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +from ...backbone_utils import BackboneConfigMixin +from ...configuration_utils import PreTrainedConfig + + +class PixioConfig(BackboneConfigMixin, PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`PixioModel`]. It is used to instantiate a + Pixio model according to the specified arguments, defining the model architecture. Instantiating a configuration + with the defaults will yield a similar configuration to that of the ViT + [facebook/pixio-huge](https://huggingface.co/facebook/pixio-huge) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + hidden_size (`int`, *optional*, defaults to 1280): + Dimensionality of the encoder layers and the pooler layer. + num_hidden_layers (`int`, *optional*, defaults to 32): + Number of hidden layers in the Transformer encoder. + num_attention_heads (`int`, *optional*, defaults to 16): + Number of attention heads for each attention layer in the Transformer encoder. + mlp_ratio (`int`, *optional*, defaults to 4): + Ratio of the hidden size of the MLPs relative to the `hidden_size`. + n_cls_tokens (`int`, *optional*, defaults to 8): + Number of class tokens in the Transformer encoder. + hidden_act (`str` or `function`, *optional*, defaults to `"gelu"`): + The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`, + `"relu"`, `"selu"` and `"gelu_new"` are supported. + hidden_dropout_prob (`float`, *optional*, defaults to 0.0): + The dropout probability for all fully connected layers in the embeddings, encoder, and pooler. + attention_probs_dropout_prob (`float`, *optional*, defaults to 0.0): + The dropout ratio for the attention probabilities. + initializer_range (`float`, *optional*, defaults to 0.02): + The standard deviation of the truncated_normal_initializer for initializing all weight matrices. + layer_norm_eps (`float`, *optional*, defaults to 1e-06): + The epsilon used by the layer normalization layers. + image_size (`int`, *optional*, defaults to 256): + The size (resolution) of each image. + patch_size (`int`, *optional*, defaults to 16): + The size (resolution) of each patch. + num_channels (`int`, *optional*, defaults to 3): + The number of input channels. + qkv_bias (`bool`, *optional*, defaults to `True`): + Whether to add a bias to the queries, keys and values. + drop_path_rate (`float`, *optional*, defaults to 0.0): + Stochastic depth rate per sample (when applied in the main path of residual layers). + out_features (`list[str]`, *optional*): + If used as backbone, list of features to output. Can be any of `"stem"`, `"stage1"`, `"stage2"`, etc. + (depending on how many stages the model has). If unset and `out_indices` is set, will default to the + corresponding stages. If unset and `out_indices` is unset, will default to the last stage. Must be in the + same order as defined in the `stage_names` attribute. + out_indices (`list[int]`, *optional*): + If used as backbone, list of indices of features to output. Can be any of 0, 1, 2, etc. (depending on how + many stages the model has). If unset and `out_features` is set, will default to the corresponding stages. + If unset and `out_features` is unset, will default to the last stage. Must be in the + same order as defined in the `stage_names` attribute. + apply_layernorm (`bool`, *optional*, defaults to `True`): + Whether to apply layer normalization to the feature maps in case the model is used as backbone. + reshape_hidden_states (`bool`, *optional*, defaults to `True`): + Whether to reshape the feature maps to 4D tensors of shape `(batch_size, hidden_size, height, width)` in + case the model is used as backbone. If `False`, the feature maps will be 3D tensors of shape `(batch_size, + seq_len, hidden_size)`. + + Example: + + ```python + >>> from transformers import PixioConfig, PixioModel + + >>> # Initializing a Pixio pixio-huge style configuration + >>> configuration = PixioConfig() + + >>> # Initializing a model (with random weights) from the pixio-huge style configuration + >>> model = PixioModel(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "pixio" + + def __init__( + self, + hidden_size=1280, + num_hidden_layers=32, + num_attention_heads=16, + mlp_ratio=4, + n_cls_tokens=8, + hidden_act="gelu", + hidden_dropout_prob=0.0, + attention_probs_dropout_prob=0.0, + initializer_range=0.02, + layer_norm_eps=1e-6, + image_size=256, + patch_size=16, + num_channels=3, + qkv_bias=True, + drop_path_rate=0.0, + out_features=None, + out_indices=None, + apply_layernorm=True, + reshape_hidden_states=True, + **kwargs, + ): + super().__init__(**kwargs) + + self.hidden_size = hidden_size + self.num_hidden_layers = num_hidden_layers + self.num_attention_heads = num_attention_heads + self.mlp_ratio = mlp_ratio + self.hidden_act = hidden_act + self.hidden_dropout_prob = hidden_dropout_prob + self.attention_probs_dropout_prob = attention_probs_dropout_prob + self.initializer_range = initializer_range + self.layer_norm_eps = layer_norm_eps + self.image_size = image_size + self.patch_size = patch_size + self.num_channels = num_channels + self.qkv_bias = qkv_bias + self.drop_path_rate = drop_path_rate + self.stage_names = ["stem"] + [f"stage{idx}" for idx in range(1, num_hidden_layers + 1)] + self.set_output_features_output_indices(out_indices=out_indices, out_features=out_features) + self.apply_layernorm = apply_layernorm + self.reshape_hidden_states = reshape_hidden_states + + self.n_cls_tokens = n_cls_tokens + + +__all__ = ["PixioConfig"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pixio/modeling_pixio.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pixio/modeling_pixio.py new file mode 100644 index 0000000000000000000000000000000000000000..41966578bbaabc09b1c52ad2596861ef8bb3c209 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pixio/modeling_pixio.py @@ -0,0 +1,508 @@ +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# This file was automatically generated from src/transformers/models/pixio/modular_pixio.py. +# Do NOT edit this file manually as any edits will be overwritten by the generation of +# the file from the modular. If any change should be done, please apply the change to the +# modular_pixio.py file directly. One of our CI enforces this. +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# Copyright 2025 Meta AI and The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import collections.abc +from collections.abc import Callable + +import torch +from torch import nn + +from ... import initialization as init +from ...activations import ACT2FN +from ...backbone_utils import BackboneMixin +from ...modeling_layers import GradientCheckpointingLayer +from ...modeling_outputs import BackboneOutput, BaseModelOutput, BaseModelOutputWithPooling +from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel +from ...processing_utils import Unpack +from ...utils import TransformersKwargs, auto_docstring, is_tracing +from ...utils.generic import merge_with_config_defaults +from ...utils.output_capturing import capture_outputs +from .configuration_pixio import PixioConfig + + +class PixioPatchEmbeddings(nn.Module): + """ + This class turns `pixel_values` of shape `(batch_size, num_channels, height, width)` into the initial + `hidden_states` (patch embeddings) of shape `(batch_size, seq_length, hidden_size)` to be consumed by a + Transformer. + """ + + def __init__(self, config: PixioConfig): + super().__init__() + image_size, patch_size = config.image_size, config.patch_size + num_channels, hidden_size = config.num_channels, config.hidden_size + + image_size = image_size if isinstance(image_size, collections.abc.Iterable) else (image_size, image_size) + patch_size = patch_size if isinstance(patch_size, collections.abc.Iterable) else (patch_size, patch_size) + num_patches = (image_size[1] // patch_size[1]) * (image_size[0] // patch_size[0]) + self.image_size = image_size + self.patch_size = patch_size + self.num_channels = num_channels + self.num_patches = num_patches + + self.projection = nn.Conv2d(num_channels, hidden_size, kernel_size=patch_size, stride=patch_size) + + def forward(self, pixel_values: torch.Tensor, interpolate_pos_encoding: bool = False) -> torch.Tensor: + batch_size, num_channels, height, width = pixel_values.shape + if num_channels != self.num_channels: + raise ValueError( + "Make sure that the channel dimension of the pixel values match with the one set in the configuration." + f" Expected {self.num_channels} but got {num_channels}." + ) + if not interpolate_pos_encoding: + if height != self.image_size[0] or width != self.image_size[1]: + raise ValueError( + f"Input image size ({height}*{width}) doesn't match model" + f" ({self.image_size[0]}*{self.image_size[1]})." + ) + embeddings = self.projection(pixel_values).flatten(2).transpose(1, 2) + return embeddings + + +class PixioEmbeddings(nn.Module): + """ + Construct the CLS tokens, position and patch embeddings. + """ + + def __init__(self, config: PixioConfig) -> None: + super().__init__() + + self.cls_token = nn.Parameter(torch.randn(1, config.n_cls_tokens, config.hidden_size)) + self.mask_token = None + self.patch_embeddings = PixioPatchEmbeddings(config) + num_patches = self.patch_embeddings.num_patches + self.position_embeddings = nn.Parameter(torch.randn(1, num_patches + config.n_cls_tokens, config.hidden_size)) + self.dropout = nn.Dropout(config.hidden_dropout_prob) + self.n_cls_tokens = config.n_cls_tokens + self.patch_size = config.patch_size + self.config = config + + def interpolate_pos_encoding(self, embeddings: torch.Tensor, height: int, width: int) -> torch.Tensor: + """ + This method allows to interpolate the pre-trained position encodings, to be able to use the model on higher resolution + images. This method is also adapted to support tracing and interpolation at torch.float32 precision. + + Adapted from: + - https://github.com/facebookresearch/dino/blob/de9ee3df6cf39fac952ab558447af1fa1365362a/vision_transformer.py#L174-L194, and + - https://github.com/facebookresearch/dinov2/blob/e1277af2ba9496fbadf7aec6eba56e8d882d1e35/dinov2/models/vision_transformer.py#L179-L211 + """ + num_patches = embeddings.shape[1] - self.n_cls_tokens + num_positions = self.position_embeddings.shape[1] - self.n_cls_tokens + + if not is_tracing() and num_patches == num_positions and height == width: + return self.position_embeddings + + class_pos_embed = self.position_embeddings[:, : self.n_cls_tokens] + patch_pos_embed = self.position_embeddings[:, self.n_cls_tokens :] + + dim = embeddings.shape[-1] + + new_height = height // self.patch_size + new_width = width // self.patch_size + + sqrt_num_positions = int(num_positions**0.5) + patch_pos_embed = patch_pos_embed.reshape(1, sqrt_num_positions, sqrt_num_positions, dim) + patch_pos_embed = patch_pos_embed.permute(0, 3, 1, 2) + target_dtype = patch_pos_embed.dtype + patch_pos_embed = nn.functional.interpolate( + patch_pos_embed.to(torch.float32), + size=(new_height, new_width), + mode="bicubic", + align_corners=False, + ).to(dtype=target_dtype) + + patch_pos_embed = patch_pos_embed.permute(0, 2, 3, 1).view(1, -1, dim) + + return torch.cat((class_pos_embed, patch_pos_embed), dim=1) + + def forward(self, pixel_values: torch.Tensor) -> torch.Tensor: + batch_size, _, height, width = pixel_values.shape + target_dtype = self.patch_embeddings.projection.weight.dtype + embeddings = self.patch_embeddings(pixel_values.to(dtype=target_dtype)) + + cls_tokens = self.cls_token.expand(batch_size, -1, -1) + embeddings = torch.cat((cls_tokens, embeddings), dim=1) + + embeddings = embeddings + self.interpolate_pos_encoding(embeddings, height, width) + + embeddings = self.dropout(embeddings) + + return embeddings + + +def eager_attention_forward( + module: nn.Module, + query: torch.Tensor, + key: torch.Tensor, + value: torch.Tensor, + attention_mask: torch.Tensor | None, + scaling: float | None = None, + dropout: float = 0.0, + **kwargs: Unpack[TransformersKwargs], +): + if scaling is None: + scaling = query.size(-1) ** -0.5 + + # Take the dot product between "query" and "key" to get the raw attention scores. + attn_weights = torch.matmul(query, key.transpose(2, 3)) * scaling + + if attention_mask is not None: + attn_weights = attn_weights + attention_mask + + attn_weights = nn.functional.softmax(attn_weights, dim=-1) + attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training) + + attn_output = torch.matmul(attn_weights, value) + attn_output = attn_output.transpose(1, 2).contiguous() + + return attn_output, attn_weights + + +class PixioSelfAttention(nn.Module): + def __init__(self, config: PixioConfig): + super().__init__() + if config.hidden_size % config.num_attention_heads != 0 and not hasattr(config, "embedding_size"): + raise ValueError( + f"The hidden size {config.hidden_size} is not a multiple of the number of attention " + f"heads {config.num_attention_heads}." + ) + + self.config = config + self.num_attention_heads = config.num_attention_heads + self.attention_head_size = int(config.hidden_size / config.num_attention_heads) + self.all_head_size = self.num_attention_heads * self.attention_head_size + self.dropout_prob = config.attention_probs_dropout_prob + self.scaling = self.attention_head_size**-0.5 + self.is_causal = False + + self.query = nn.Linear(config.hidden_size, self.all_head_size, bias=config.qkv_bias) + self.key = nn.Linear(config.hidden_size, self.all_head_size, bias=config.qkv_bias) + self.value = nn.Linear(config.hidden_size, self.all_head_size, bias=config.qkv_bias) + + def forward(self, hidden_states: torch.Tensor) -> tuple[torch.Tensor, torch.Tensor]: + batch_size = hidden_states.shape[0] + new_shape = batch_size, -1, self.num_attention_heads, self.attention_head_size + + key_layer = self.key(hidden_states).view(*new_shape).transpose(1, 2) + value_layer = self.value(hidden_states).view(*new_shape).transpose(1, 2) + query_layer = self.query(hidden_states).view(*new_shape).transpose(1, 2) + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, eager_attention_forward + ) + + context_layer, attention_probs = attention_interface( + self, + query_layer, + key_layer, + value_layer, + None, + is_causal=self.is_causal, + scaling=self.scaling, + dropout=0.0 if not self.training else self.dropout_prob, + ) + + new_context_layer_shape = context_layer.size()[:-2] + (self.all_head_size,) + context_layer = context_layer.reshape(new_context_layer_shape) + + return context_layer, attention_probs + + +class PixioSelfOutput(nn.Module): + """ + The residual connection is defined in PixioLayer instead of here (as is the case with other models), due to the + layernorm applied before each block. + """ + + def __init__(self, config: PixioConfig): + super().__init__() + self.dense = nn.Linear(config.hidden_size, config.hidden_size) + self.dropout = nn.Dropout(config.hidden_dropout_prob) + + def forward(self, hidden_states: torch.Tensor, input_tensor: torch.Tensor) -> torch.Tensor: + hidden_states = self.dense(hidden_states) + hidden_states = self.dropout(hidden_states) + return hidden_states + + +class PixioAttention(nn.Module): + def __init__(self, config: PixioConfig): + super().__init__() + self.attention = PixioSelfAttention(config) + self.output = PixioSelfOutput(config) + + def forward(self, hidden_states: torch.Tensor) -> torch.Tensor: + self_attn_output, _ = self.attention(hidden_states) + output = self.output(self_attn_output, hidden_states) + return output + + +def drop_path(input: torch.Tensor, drop_prob: float = 0.0, training: bool = False) -> torch.Tensor: + """ + Drop paths (Stochastic Depth) per sample (when applied in main path of residual blocks). + + """ + if drop_prob == 0.0 or not training: + return input + keep_prob = 1 - drop_prob + shape = (input.shape[0],) + (1,) * (input.ndim - 1) # work with diff dim tensors, not just 2D ConvNets + random_tensor = keep_prob + torch.rand(shape, dtype=input.dtype, device=input.device) + random_tensor.floor_() # binarize + output = input.div(keep_prob) * random_tensor + return output + + +class PixioDropPath(nn.Module): + """Drop paths (Stochastic Depth) per sample (when applied in main path of residual blocks).""" + + def __init__(self, drop_prob: float | None = None) -> None: + super().__init__() + self.drop_prob = drop_prob + + def forward(self, hidden_states: torch.Tensor) -> torch.Tensor: + return drop_path(hidden_states, self.drop_prob, self.training) + + def extra_repr(self) -> str: + return f"p={self.drop_prob}" + + +class PixioMLP(nn.Module): + def __init__(self, config) -> None: + super().__init__() + in_features = out_features = config.hidden_size + hidden_features = int(config.hidden_size * config.mlp_ratio) + self.fc1 = nn.Linear(in_features, hidden_features, bias=True) + if isinstance(config.hidden_act, str): + self.activation = ACT2FN[config.hidden_act] + else: + self.activation = config.hidden_act + self.fc2 = nn.Linear(hidden_features, out_features, bias=True) + + def forward(self, hidden_state: torch.Tensor) -> torch.Tensor: + hidden_state = self.fc1(hidden_state) + hidden_state = self.activation(hidden_state) + hidden_state = self.fc2(hidden_state) + return hidden_state + + +class PixioLayer(GradientCheckpointingLayer): + def __init__(self, config: PixioConfig) -> None: + super().__init__() + + self.norm1 = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps) + self.attention = PixioAttention(config) + self.drop_path = PixioDropPath(config.drop_path_rate) if config.drop_path_rate > 0.0 else nn.Identity() + + self.norm2 = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps) + self.mlp = PixioMLP(config) + + def forward(self, hidden_states: torch.Tensor) -> torch.Tensor: + hidden_states_norm = self.norm1(hidden_states) + self_attention_output = self.attention(hidden_states_norm) + + hidden_states = self.drop_path(self_attention_output) + hidden_states + + layer_output = self.norm2(hidden_states) + layer_output = self.mlp(layer_output) + + layer_output = self.drop_path(layer_output) + hidden_states + + return layer_output + + +class PixioEncoder(nn.Module): + def __init__(self, config: PixioConfig): + super().__init__() + self.config = config + self.layer = nn.ModuleList([PixioLayer(config) for _ in range(config.num_hidden_layers)]) + self.gradient_checkpointing = False + + def forward(self, hidden_states: torch.Tensor, output_hidden_states: bool = False) -> BaseModelOutput: + all_hidden_states = [hidden_states] if output_hidden_states else None + for i, layer_module in enumerate(self.layer): + hidden_states = layer_module(hidden_states) + if all_hidden_states: + all_hidden_states.append(hidden_states) + + return BaseModelOutput( + last_hidden_state=hidden_states, + hidden_states=tuple(all_hidden_states) if all_hidden_states else None, + ) + + +@auto_docstring +class PixioPreTrainedModel(PreTrainedModel): + config: PixioConfig + base_model_prefix = "pixio" + main_input_name = "pixel_values" + input_modalities = ("image",) + supports_gradient_checkpointing = True + _no_split_modules = ["PixioEmbeddings", "PixioLayer"] + _supports_sdpa = True + _supports_flash_attn = True + _supports_flex_attn = True + _supports_attention_backend = True + _can_record_outputs = { + "hidden_states": PixioLayer, + "attentions": PixioSelfAttention, + } + + @torch.no_grad() + def _init_weights(self, module: nn.Linear | nn.Conv2d | nn.LayerNorm): + """Initialize the weights""" + if isinstance(module, (nn.Linear, nn.Conv2d)): + init.trunc_normal_(module.weight, mean=0.0, std=self.config.initializer_range) + if module.bias is not None: + init.zeros_(module.bias) + elif isinstance(module, nn.LayerNorm): + init.zeros_(module.bias) + init.ones_(module.weight) + elif isinstance(module, PixioEmbeddings): + init.trunc_normal_(module.position_embeddings, mean=0.0, std=self.config.initializer_range) + init.trunc_normal_(module.cls_token, mean=0.0, std=self.config.initializer_range) + if module.mask_token is not None: + init.zeros_(module.mask_token) + + +@auto_docstring +class PixioModel(PixioPreTrainedModel): + def __init__(self, config: PixioConfig): + super().__init__(config) + self.config = config + + self.embeddings = PixioEmbeddings(config) + self.encoder = PixioEncoder(config) + + self.layernorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps) + + self.post_init() + + def get_input_embeddings(self) -> PixioPatchEmbeddings: + return self.embeddings.patch_embeddings + + @merge_with_config_defaults + @capture_outputs(tie_last_hidden_states=False) + @auto_docstring + def forward( + self, + pixel_values: torch.Tensor | None = None, + output_hidden_states: bool | None = None, + **kwargs, + ) -> BaseModelOutputWithPooling: + if output_hidden_states is None: + output_hidden_states = self.config.output_hidden_states + + if pixel_values is None: + raise ValueError("You have to specify pixel_values") + + embedding_output = self.embeddings(pixel_values) + + encoder_outputs: BaseModelOutput = self.encoder(embedding_output, output_hidden_states=output_hidden_states) + sequence_output = encoder_outputs.last_hidden_state + sequence_output = self.layernorm(sequence_output) + pooled_output = sequence_output[:, : self.embeddings.n_cls_tokens, :].mean(dim=1) + + return BaseModelOutputWithPooling( + last_hidden_state=sequence_output, + pooler_output=pooled_output, + hidden_states=encoder_outputs.hidden_states, + ) + + +@auto_docstring( + custom_intro=""" + Pixio backbone, to be used with frameworks like DETR and MaskFormer. + """ +) +class PixioBackbone(BackboneMixin, PixioPreTrainedModel): + def __init__(self, config): + super().__init__(config) + + self.num_features = [config.hidden_size for _ in range(config.num_hidden_layers + 1)] + self.embeddings = PixioEmbeddings(config) + self.encoder = PixioEncoder(config) + + self.layernorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps) + + # Initialize weights and apply final processing + self.post_init() + + def get_input_embeddings(self) -> PixioPatchEmbeddings: + return self.embeddings.patch_embeddings + + @merge_with_config_defaults + @capture_outputs + @auto_docstring + def forward( + self, pixel_values: torch.Tensor, output_hidden_states: bool | None = None, **kwargs + ) -> BackboneOutput: + r""" + Examples: + + ```python + >>> from transformers import AutoImageProcessor, AutoBackbone + >>> import torch + >>> from PIL import Image + >>> import httpx + >>> from io import BytesIO + + >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg" + >>> with httpx.stream("GET", url) as response: + ... image = Image.open(BytesIO(response.read())) + + >>> processor = AutoImageProcessor.from_pretrained("facebook/pixio-huge") + >>> model = AutoBackbone.from_pretrained( + ... "facebook/pixio-huge", out_features=["stage7", "stage15", "stage23", "stage31"] + ... ) + + >>> inputs = processor(image, return_tensors="pt") + + >>> outputs = model(**inputs) + >>> feature_maps = outputs.feature_maps + >>> list(feature_maps[-1].shape) + [1, 1280, 16, 16] + ```""" + if output_hidden_states is None: + output_hidden_states = self.config.output_hidden_states + + embedding_output = self.embeddings(pixel_values) + output: BaseModelOutput = self.encoder(embedding_output, output_hidden_states=True) + hidden_states = output.hidden_states + + feature_maps = [] + for stage, hidden_state in zip(self.stage_names, hidden_states): + if stage in self.out_features: + if self.config.apply_layernorm: + hidden_state = self.layernorm(hidden_state) + if self.config.reshape_hidden_states: + hidden_state = hidden_state[:, self.embeddings.n_cls_tokens :] + batch_size, _, height, width = pixel_values.shape + patch_size = self.config.patch_size + hidden_state = hidden_state.reshape(batch_size, height // patch_size, width // patch_size, -1) + hidden_state = hidden_state.permute(0, 3, 1, 2).contiguous() + feature_maps.append(hidden_state) + + return BackboneOutput( + feature_maps=tuple(feature_maps), + hidden_states=hidden_states if output_hidden_states else None, + ) + + +__all__ = ["PixioModel", "PixioPreTrainedModel", "PixioBackbone"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pixio/modular_pixio.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pixio/modular_pixio.py new file mode 100644 index 0000000000000000000000000000000000000000..c006720de83291f9e66ba4fa4e0bd9ead7fad11d --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pixio/modular_pixio.py @@ -0,0 +1,406 @@ +# Copyright 2025 Meta AI and The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""PyTorch Pixio model.""" + +import torch +from torch import nn + +from ...modeling_layers import GradientCheckpointingLayer +from ...modeling_outputs import BackboneOutput, BaseModelOutput, BaseModelOutputWithPooling +from ...utils import auto_docstring, is_tracing, logging +from ...utils.generic import merge_with_config_defaults +from ...utils.output_capturing import capture_outputs +from ..dinov2.configuration_dinov2 import Dinov2Config +from ..dinov2.modeling_dinov2 import ( + Dinov2Backbone, + Dinov2DropPath, + Dinov2MLP, +) +from ..vit.modeling_vit import ViTAttention, ViTPatchEmbeddings, ViTPreTrainedModel + + +logger = logging.get_logger(__name__) + + +class PixioConfig(Dinov2Config): + r""" + This is the configuration class to store the configuration of a [`PixioModel`]. It is used to instantiate a + Pixio model according to the specified arguments, defining the model architecture. Instantiating a configuration + with the defaults will yield a similar configuration to that of the ViT + [facebook/pixio-huge](https://huggingface.co/facebook/pixio-huge) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + hidden_size (`int`, *optional*, defaults to 1280): + Dimensionality of the encoder layers and the pooler layer. + num_hidden_layers (`int`, *optional*, defaults to 32): + Number of hidden layers in the Transformer encoder. + num_attention_heads (`int`, *optional*, defaults to 16): + Number of attention heads for each attention layer in the Transformer encoder. + mlp_ratio (`int`, *optional*, defaults to 4): + Ratio of the hidden size of the MLPs relative to the `hidden_size`. + n_cls_tokens (`int`, *optional*, defaults to 8): + Number of class tokens in the Transformer encoder. + hidden_act (`str` or `function`, *optional*, defaults to `"gelu"`): + The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`, + `"relu"`, `"selu"` and `"gelu_new"` are supported. + hidden_dropout_prob (`float`, *optional*, defaults to 0.0): + The dropout probability for all fully connected layers in the embeddings, encoder, and pooler. + attention_probs_dropout_prob (`float`, *optional*, defaults to 0.0): + The dropout ratio for the attention probabilities. + initializer_range (`float`, *optional*, defaults to 0.02): + The standard deviation of the truncated_normal_initializer for initializing all weight matrices. + layer_norm_eps (`float`, *optional*, defaults to 1e-06): + The epsilon used by the layer normalization layers. + image_size (`int`, *optional*, defaults to 256): + The size (resolution) of each image. + patch_size (`int`, *optional*, defaults to 16): + The size (resolution) of each patch. + num_channels (`int`, *optional*, defaults to 3): + The number of input channels. + qkv_bias (`bool`, *optional*, defaults to `True`): + Whether to add a bias to the queries, keys and values. + drop_path_rate (`float`, *optional*, defaults to 0.0): + Stochastic depth rate per sample (when applied in the main path of residual layers). + out_features (`list[str]`, *optional*): + If used as backbone, list of features to output. Can be any of `"stem"`, `"stage1"`, `"stage2"`, etc. + (depending on how many stages the model has). If unset and `out_indices` is set, will default to the + corresponding stages. If unset and `out_indices` is unset, will default to the last stage. Must be in the + same order as defined in the `stage_names` attribute. + out_indices (`list[int]`, *optional*): + If used as backbone, list of indices of features to output. Can be any of 0, 1, 2, etc. (depending on how + many stages the model has). If unset and `out_features` is set, will default to the corresponding stages. + If unset and `out_features` is unset, will default to the last stage. Must be in the + same order as defined in the `stage_names` attribute. + apply_layernorm (`bool`, *optional*, defaults to `True`): + Whether to apply layer normalization to the feature maps in case the model is used as backbone. + reshape_hidden_states (`bool`, *optional*, defaults to `True`): + Whether to reshape the feature maps to 4D tensors of shape `(batch_size, hidden_size, height, width)` in + case the model is used as backbone. If `False`, the feature maps will be 3D tensors of shape `(batch_size, + seq_len, hidden_size)`. + + Example: + + ```python + >>> from transformers import PixioConfig, PixioModel + + >>> # Initializing a Pixio pixio-huge style configuration + >>> configuration = PixioConfig() + + >>> # Initializing a model (with random weights) from the pixio-huge style configuration + >>> model = PixioModel(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "pixio" + + def __init__( + self, + hidden_size=1280, + num_hidden_layers=32, + num_attention_heads=16, + mlp_ratio=4, + n_cls_tokens=8, + hidden_act="gelu", + hidden_dropout_prob=0.0, + attention_probs_dropout_prob=0.0, + initializer_range=0.02, + layer_norm_eps=1e-6, + image_size=256, + patch_size=16, + num_channels=3, + qkv_bias=True, + drop_path_rate=0.0, + out_features=None, + out_indices=None, + apply_layernorm=True, + reshape_hidden_states=True, + **kwargs, + ): + super().__init__( + hidden_size=hidden_size, + num_hidden_layers=num_hidden_layers, + num_attention_heads=num_attention_heads, + mlp_ratio=mlp_ratio, + hidden_act=hidden_act, + hidden_dropout_prob=hidden_dropout_prob, + attention_probs_dropout_prob=attention_probs_dropout_prob, + initializer_range=initializer_range, + layer_norm_eps=layer_norm_eps, + image_size=image_size, + patch_size=patch_size, + num_channels=num_channels, + qkv_bias=qkv_bias, + drop_path_rate=drop_path_rate, + apply_layernorm=apply_layernorm, + reshape_hidden_states=reshape_hidden_states, + ) + + self.n_cls_tokens = n_cls_tokens + + del self.layerscale_value + del self.use_swiglu_ffn + del self.use_mask_token + + +class PixioPatchEmbeddings(ViTPatchEmbeddings): + pass + + +class PixioEmbeddings(nn.Module): + """ + Construct the CLS tokens, position and patch embeddings. + """ + + def __init__(self, config: PixioConfig) -> None: + super().__init__() + + self.cls_token = nn.Parameter(torch.randn(1, config.n_cls_tokens, config.hidden_size)) + self.mask_token = None + self.patch_embeddings = PixioPatchEmbeddings(config) + num_patches = self.patch_embeddings.num_patches + self.position_embeddings = nn.Parameter(torch.randn(1, num_patches + config.n_cls_tokens, config.hidden_size)) + self.dropout = nn.Dropout(config.hidden_dropout_prob) + self.n_cls_tokens = config.n_cls_tokens + self.patch_size = config.patch_size + self.config = config + + def interpolate_pos_encoding(self, embeddings: torch.Tensor, height: int, width: int) -> torch.Tensor: + """ + This method allows to interpolate the pre-trained position encodings, to be able to use the model on higher resolution + images. This method is also adapted to support tracing and interpolation at torch.float32 precision. + + Adapted from: + - https://github.com/facebookresearch/dino/blob/de9ee3df6cf39fac952ab558447af1fa1365362a/vision_transformer.py#L174-L194, and + - https://github.com/facebookresearch/dinov2/blob/e1277af2ba9496fbadf7aec6eba56e8d882d1e35/dinov2/models/vision_transformer.py#L179-L211 + """ + num_patches = embeddings.shape[1] - self.n_cls_tokens + num_positions = self.position_embeddings.shape[1] - self.n_cls_tokens + + if not is_tracing() and num_patches == num_positions and height == width: + return self.position_embeddings + + class_pos_embed = self.position_embeddings[:, : self.n_cls_tokens] + patch_pos_embed = self.position_embeddings[:, self.n_cls_tokens :] + + dim = embeddings.shape[-1] + + new_height = height // self.patch_size + new_width = width // self.patch_size + + sqrt_num_positions = int(num_positions**0.5) + patch_pos_embed = patch_pos_embed.reshape(1, sqrt_num_positions, sqrt_num_positions, dim) + patch_pos_embed = patch_pos_embed.permute(0, 3, 1, 2) + target_dtype = patch_pos_embed.dtype + patch_pos_embed = nn.functional.interpolate( + patch_pos_embed.to(torch.float32), + size=(new_height, new_width), + mode="bicubic", + align_corners=False, + ).to(dtype=target_dtype) + + patch_pos_embed = patch_pos_embed.permute(0, 2, 3, 1).view(1, -1, dim) + + return torch.cat((class_pos_embed, patch_pos_embed), dim=1) + + def forward(self, pixel_values: torch.Tensor) -> torch.Tensor: + batch_size, _, height, width = pixel_values.shape + target_dtype = self.patch_embeddings.projection.weight.dtype + embeddings = self.patch_embeddings(pixel_values.to(dtype=target_dtype)) + + cls_tokens = self.cls_token.expand(batch_size, -1, -1) + embeddings = torch.cat((cls_tokens, embeddings), dim=1) + + embeddings = embeddings + self.interpolate_pos_encoding(embeddings, height, width) + + embeddings = self.dropout(embeddings) + + return embeddings + + +class PixioAttention(ViTAttention): + pass + + +class PixioDropPath(Dinov2DropPath): + pass + + +class PixioMLP(Dinov2MLP): + pass + + +class PixioLayer(GradientCheckpointingLayer): + def __init__(self, config: PixioConfig) -> None: + super().__init__() + + self.norm1 = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps) + self.attention = PixioAttention(config) + self.drop_path = PixioDropPath(config.drop_path_rate) if config.drop_path_rate > 0.0 else nn.Identity() + + self.norm2 = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps) + self.mlp = PixioMLP(config) + + def forward(self, hidden_states: torch.Tensor) -> torch.Tensor: + hidden_states_norm = self.norm1(hidden_states) + self_attention_output = self.attention(hidden_states_norm) + + hidden_states = self.drop_path(self_attention_output) + hidden_states + + layer_output = self.norm2(hidden_states) + layer_output = self.mlp(layer_output) + + layer_output = self.drop_path(layer_output) + hidden_states + + return layer_output + + +class PixioEncoder(nn.Module): + def __init__(self, config: PixioConfig): + super().__init__() + self.config = config + self.layer = nn.ModuleList([PixioLayer(config) for _ in range(config.num_hidden_layers)]) + self.gradient_checkpointing = False + + def forward(self, hidden_states: torch.Tensor, output_hidden_states: bool = False) -> BaseModelOutput: + all_hidden_states = [hidden_states] if output_hidden_states else None + for i, layer_module in enumerate(self.layer): + hidden_states = layer_module(hidden_states) + if all_hidden_states: + all_hidden_states.append(hidden_states) + + return BaseModelOutput( + last_hidden_state=hidden_states, + hidden_states=tuple(all_hidden_states) if all_hidden_states else None, + ) + + +class PixioPreTrainedModel(ViTPreTrainedModel): + pass + + +@auto_docstring +class PixioModel(PixioPreTrainedModel): + def __init__(self, config: PixioConfig): + super().__init__(config) + self.config = config + + self.embeddings = PixioEmbeddings(config) + self.encoder = PixioEncoder(config) + + self.layernorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps) + + self.post_init() + + def get_input_embeddings(self) -> PixioPatchEmbeddings: + return self.embeddings.patch_embeddings + + @merge_with_config_defaults + @capture_outputs(tie_last_hidden_states=False) + @auto_docstring + def forward( + self, + pixel_values: torch.Tensor | None = None, + output_hidden_states: bool | None = None, + **kwargs, + ) -> BaseModelOutputWithPooling: + if output_hidden_states is None: + output_hidden_states = self.config.output_hidden_states + + if pixel_values is None: + raise ValueError("You have to specify pixel_values") + + embedding_output = self.embeddings(pixel_values) + + encoder_outputs: BaseModelOutput = self.encoder(embedding_output, output_hidden_states=output_hidden_states) + sequence_output = encoder_outputs.last_hidden_state + sequence_output = self.layernorm(sequence_output) + pooled_output = sequence_output[:, : self.embeddings.n_cls_tokens, :].mean(dim=1) + + return BaseModelOutputWithPooling( + last_hidden_state=sequence_output, + pooler_output=pooled_output, + hidden_states=encoder_outputs.hidden_states, + ) + + +@auto_docstring( + custom_intro=""" + Pixio backbone, to be used with frameworks like DETR and MaskFormer. + """ +) +class PixioBackbone(Dinov2Backbone): + @merge_with_config_defaults + @capture_outputs + @auto_docstring + def forward( + self, pixel_values: torch.Tensor, output_hidden_states: bool | None = None, **kwargs + ) -> BackboneOutput: + r""" + Examples: + + ```python + >>> from transformers import AutoImageProcessor, AutoBackbone + >>> import torch + >>> from PIL import Image + >>> import httpx + >>> from io import BytesIO + + >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg" + >>> with httpx.stream("GET", url) as response: + ... image = Image.open(BytesIO(response.read())) + + >>> processor = AutoImageProcessor.from_pretrained("facebook/pixio-huge") + >>> model = AutoBackbone.from_pretrained( + ... "facebook/pixio-huge", out_features=["stage7", "stage15", "stage23", "stage31"] + ... ) + + >>> inputs = processor(image, return_tensors="pt") + + >>> outputs = model(**inputs) + >>> feature_maps = outputs.feature_maps + >>> list(feature_maps[-1].shape) + [1, 1280, 16, 16] + ```""" + if output_hidden_states is None: + output_hidden_states = self.config.output_hidden_states + + embedding_output = self.embeddings(pixel_values) + output: BaseModelOutput = self.encoder(embedding_output, output_hidden_states=True) + hidden_states = output.hidden_states + + feature_maps = [] + for stage, hidden_state in zip(self.stage_names, hidden_states): + if stage in self.out_features: + if self.config.apply_layernorm: + hidden_state = self.layernorm(hidden_state) + if self.config.reshape_hidden_states: + hidden_state = hidden_state[:, self.embeddings.n_cls_tokens :] + batch_size, _, height, width = pixel_values.shape + patch_size = self.config.patch_size + hidden_state = hidden_state.reshape(batch_size, height // patch_size, width // patch_size, -1) + hidden_state = hidden_state.permute(0, 3, 1, 2).contiguous() + feature_maps.append(hidden_state) + + return BackboneOutput( + feature_maps=tuple(feature_maps), + hidden_states=hidden_states if output_hidden_states else None, + ) + + +__all__ = ["PixioConfig", "PixioModel", "PixioPreTrainedModel", "PixioBackbone"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pixtral/__init__.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pixtral/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..8afbbfb1f47f71d478a9ed475f36719d405b4124 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pixtral/__init__.py @@ -0,0 +1,30 @@ +# Copyright 2024 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from typing import TYPE_CHECKING + +from ...utils import _LazyModule +from ...utils.import_utils import define_import_structure + + +if TYPE_CHECKING: + from .configuration_pixtral import * + from .image_processing_pixtral import * + from .image_processing_pixtral_fast import * + from .modeling_pixtral import * + from .processing_pixtral import * +else: + import sys + + _file = globals()["__file__"] + sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__) diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pixtral/configuration_pixtral.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pixtral/configuration_pixtral.py new file mode 100644 index 0000000000000000000000000000000000000000..d856aa35fa61973736d78e5d7fd9f770bb63c880 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pixtral/configuration_pixtral.py @@ -0,0 +1,106 @@ +# Copyright 2024 HuggingFace Inc. team. All rights reserved. +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""Pixtral model configuration""" + +from ...configuration_utils import PreTrainedConfig +from ...modeling_rope_utils import RopeParameters +from ...utils import logging + + +logger = logging.get_logger(__name__) + + +class PixtralVisionConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`PixtralVisionModel`]. It is used to instantiate an + Pixtral vision encoder according to the specified arguments, defining the model architecture. Instantiating a configuration + with the defaults will yield a similar configuration to the vision encoder used by Pixtral-12B. + + e.g. [pixtral-hf/pixtral-9b](https://huggingface.co/pixtral-hf/pixtral-9b) + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + hidden_size (`int`, *optional*, defaults to 1024): + Dimension of the hidden representations. + intermediate_size (`int`, *optional*, defaults to 4096): + Dimension of the MLP representations. + num_hidden_layers (`int`, *optional*, defaults to 24): + Number of hidden layers in the Transformer encoder. + num_attention_heads (`int`, *optional*, defaults to 16): + Number of attention heads in the Transformer encoder. + num_channels (`int`, *optional*, defaults to 3): + Number of input channels in the input images. + image_size (`int`, *optional*, defaults to 1024): + Max dimension of the input images. + patch_size (`int`, *optional*, defaults to 16): + Size of the image patches. + hidden_act (`str`, *optional*, defaults to `"gelu"`): + Activation function used in the hidden layers. + attention_dropout (`float`, *optional*, defaults to 0.0): + Dropout probability for the attention layers. + rope_parameters (`RopeParameters`, *optional*): + The RopeParameters + initializer_range (`float`, *optional*, defaults to 0.02): + The standard deviation of the truncated_normal_initializer for initializing all weight matrices. + + Example: + + ```python + >>> from transformers import PixtralVisionModel, PixtralVisionConfig + + >>> # Initializing a Pixtral-12B style configuration + >>> config = PixtralVisionConfig() + + >>> # Initializing a model (with randomly initialized weights) from the configuration + >>> model = PixtralVisionModel(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "pixtral" + + def __init__( + self, + hidden_size: int | None = 1024, + intermediate_size: int | None = 4096, + num_hidden_layers: int | None = 24, + num_attention_heads: int | None = 16, + num_channels: int | None = 3, + image_size: int | None = 1024, + patch_size: int | None = 16, + hidden_act: str | None = "gelu", + attention_dropout: float | None = 0.0, + rope_parameters: RopeParameters | dict[str, RopeParameters] | None = None, + initializer_range: float | None = 0.02, + **kwargs, + ): + self.hidden_size = hidden_size + self.intermediate_size = intermediate_size + self.num_hidden_layers = num_hidden_layers + self.num_attention_heads = num_attention_heads + self.num_channels = num_channels + self.patch_size = patch_size + self.image_size = image_size + self.attention_dropout = attention_dropout + self.hidden_act = hidden_act + self.head_dim = hidden_size // num_attention_heads + self.initializer_range = initializer_range + self.rope_parameters = rope_parameters + + super().__init__(**kwargs) + + +__all__ = ["PixtralVisionConfig"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pixtral/image_processing_pixtral.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pixtral/image_processing_pixtral.py new file mode 100644 index 0000000000000000000000000000000000000000..a9ab86582869b08013b701e8a1c6092e60f56157 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pixtral/image_processing_pixtral.py @@ -0,0 +1,477 @@ +# Copyright 2024 The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""Image processor class for Pixtral.""" + +import math + +import numpy as np + +from ...image_processing_utils import BaseImageProcessor, BatchFeature, get_size_dict +from ...image_transforms import ( + pad, + resize, + to_channel_dimension_format, +) +from ...image_utils import ( + ChannelDimension, + ImageInput, + PILImageResampling, + get_image_size, + infer_channel_dimension_format, + is_scaled_image, + make_flat_list_of_images, + to_numpy_array, + valid_images, + validate_kwargs, + validate_preprocess_arguments, +) +from ...processing_utils import ImagesKwargs +from ...utils import TensorType, is_vision_available, logging +from ...utils.import_utils import requires_backends + + +logger = logging.get_logger(__name__) + + +if is_vision_available(): + import PIL + + +class PixtralImageProcessorKwargs(ImagesKwargs, total=False): + """ + patch_size (`Union[dict[str, int], int]` *optional*, defaults to `{"height": 16, "width": 16}`): + Size of the patches in the model, used to calculate the output image size. Can be overridden by `patch_size` in the `preprocess` method. + """ + + patch_size: dict[str, int] | int + + +# Adapted from function in image_transforms.py to ensure any transparent pixels are converted to white. +def convert_to_rgb(image: ImageInput) -> ImageInput: + """ + Converts an image to RGB format. Only converts if the image is of type PIL.Image.Image, otherwise returns the image + as is. + Args: + image (Image): + The image to convert. + """ + requires_backends(convert_to_rgb, ["vision"]) + + if not isinstance(image, PIL.Image.Image): + return image + + if image.mode == "RGB": + return image + + # First we convert to RGBA to set background to white. + image = image.convert("RGBA") + + # Create a new image with a white background. + new_image = PIL.Image.new("RGBA", image.size, "WHITE") + new_image.paste(image, (0, 0), image) + new_image = new_image.convert("RGB") + return new_image + + +def _num_image_tokens(image_size: tuple[int, int], patch_size: tuple[int, int]) -> int: + """ + Calculate the number of image tokens given the image size and patch size. + + Args: + image_size (`tuple[int, int]`): + The size of the image as `(height, width)`. + patch_size (`tuple[int, int]`): + The patch size as `(height, width)`. + + Returns: + `int`: The number of image tokens. + """ + height, width = image_size + patch_height, patch_width = patch_size if isinstance(patch_size, (tuple, list)) else (patch_size, patch_size) + num_width_tokens = (width - 1) // patch_width + 1 + num_height_tokens = (height - 1) // patch_height + 1 + return num_height_tokens, num_width_tokens + + +def get_resize_output_image_size( + input_image: ImageInput, + size: int | tuple[int, int] | list[int] | tuple[int], + patch_size: int | tuple[int, int] | list[int] | tuple[int], + input_data_format: str | ChannelDimension | None = None, +) -> tuple: + """ + Find the target (height, width) dimension of the output image after resizing given the input image and the desired + size. + + Args: + input_image (`ImageInput`): + The image to resize. + size (`int` or `tuple[int, int]`): + Max image size an input image can be. Must be a dictionary with the key "longest_edge". + patch_size (`int` or `tuple[int, int]`): + The patch_size as `(height, width)` to use for resizing the image. If patch_size is an integer, `(patch_size, patch_size)` + will be used + input_data_format (`ChannelDimension`, *optional*): + The channel dimension format of the input image. If unset, will use the inferred format from the input. + + Returns: + `tuple`: The target (height, width) dimension of the output image after resizing. + """ + max_height, max_width = size if isinstance(size, (tuple, list)) else (size, size) + patch_height, patch_width = patch_size if isinstance(patch_size, (tuple, list)) else (patch_size, patch_size) + height, width = get_image_size(input_image, input_data_format) + + ratio = max(height / max_height, width / max_width) + + if ratio > 1: + # Original implementation uses `round` which utilises bankers rounding, which can lead to surprising results + # Here we use floor to ensure the image is always smaller than the given "longest_edge" + height = int(math.floor(height / ratio)) + width = int(math.floor(width / ratio)) + + num_height_tokens, num_width_tokens = _num_image_tokens((height, width), (patch_height, patch_width)) + return num_height_tokens * patch_height, num_width_tokens * patch_width + + +class PixtralImageProcessor(BaseImageProcessor): + r""" + Constructs a Pixtral image processor. + + Args: + do_resize (`bool`, *optional*, defaults to `True`): + Whether to resize the image's (height, width) dimensions to the specified `size`. Can be overridden by + `do_resize` in the `preprocess` method. + size (`dict[str, int]` *optional*, defaults to `{"longest_edge": 1024}`): + Size of the maximum dimension of either the height or width dimension of the image. Used to control how + images are resized. If either the height or width are greater than `size["longest_edge"]` then both the height and width are rescaled by `height / ratio`, `width /ratio` where `ratio = max(height / longest_edge, width / longest_edge)` + patch_size (`dict[str, int]` *optional*, defaults to `{"height": 16, "width": 16}`): + Size of the patches in the model, used to calculate the output image size. Can be overridden by `patch_size` in the `preprocess` method. + resample (`PILImageResampling`, *optional*, defaults to `Resampling.BICUBIC`): + Resampling filter to use if resizing the image. Can be overridden by `resample` in the `preprocess` method. + do_rescale (`bool`, *optional*, defaults to `True`): + Whether to rescale the image by the specified scale `rescale_factor`. Can be overridden by `do_rescale` in + the `preprocess` method. + rescale_factor (`int` or `float`, *optional*, defaults to `1/255`): + Scale factor to use if rescaling the image. Can be overridden by `rescale_factor` in the `preprocess` + method. + do_normalize (`bool`, *optional*, defaults to `True`): + Whether to normalize the image. Can be overridden by `do_normalize` in the `preprocess` method. + image_mean (`float` or `list[float]`, *optional*, defaults to `[0.48145466, 0.4578275, 0.40821073]`): + Mean to use if normalizing the image. This is a float or list of floats the length of the number of + channels in the image. Can be overridden by the `image_mean` parameter in the `preprocess` method. + image_std (`float` or `list[float]`, *optional*, defaults to `[0.26862954, 0.26130258, 0.27577711]`): + Standard deviation to use if normalizing the image. This is a float or list of floats the length of the + number of channels in the image. Can be overridden by the `image_std` parameter in the `preprocess` method. + Can be overridden by the `image_std` parameter in the `preprocess` method. + do_convert_rgb (`bool`, *optional*, defaults to `True`): + Whether to convert the image to RGB. + """ + + model_input_names = ["pixel_values", "image_sizes"] + valid_kwargs = PixtralImageProcessorKwargs + + def __init__( + self, + do_resize: bool = True, + size: dict[str, int] | None = None, + patch_size: dict[str, int] | None = None, + resample: PILImageResampling = PILImageResampling.BICUBIC, + do_rescale: bool = True, + rescale_factor: int | float = 1 / 255, + do_normalize: bool = True, + image_mean: float | list[float] | None = None, + image_std: float | list[float] | None = None, + do_convert_rgb: bool = True, + **kwargs, + ) -> None: + super().__init__(**kwargs) + size = size if size is not None else {"longest_edge": 1024} + patch_size = patch_size if patch_size is not None else {"height": 16, "width": 16} + patch_size = get_size_dict(patch_size, default_to_square=True) + + self.do_resize = do_resize + self.size = size + self.patch_size = patch_size + self.resample = resample + self.do_rescale = do_rescale + self.rescale_factor = rescale_factor + self.do_normalize = do_normalize + self.image_mean = image_mean if image_mean is not None else [0.48145466, 0.4578275, 0.40821073] + self.image_std = image_std if image_std is not None else [0.26862954, 0.26130258, 0.27577711] + self.do_convert_rgb = do_convert_rgb + self._valid_processor_keys = [ + "images", + "do_resize", + "size", + "patch_size", + "resample", + "do_rescale", + "rescale_factor", + "do_normalize", + "image_mean", + "image_std", + "do_convert_rgb", + "return_tensors", + "data_format", + "input_data_format", + ] + + def resize( + self, + image: np.ndarray, + size: dict[str, int], + patch_size: dict[str, int], + resample: PILImageResampling = PILImageResampling.BICUBIC, + data_format: str | ChannelDimension | None = None, + input_data_format: str | ChannelDimension | None = None, + **kwargs, + ) -> np.ndarray: + """ + Resize an image. The shortest edge of the image is resized to size["shortest_edge"], with the longest edge + resized to keep the input aspect ratio. + + Args: + image (`np.ndarray`): + Image to resize. + size (`dict[str, int]`): + Dict containing the longest possible edge of the image. + patch_size (`dict[str, int]`): + Patch size used to calculate the size of the output image. + resample (`PILImageResampling`, *optional*, defaults to `PILImageResampling.BICUBIC`): + Resampling filter to use when resiizing the image. + data_format (`str` or `ChannelDimension`, *optional*): + The channel dimension format of the image. If not provided, it will be the same as the input image. + input_data_format (`ChannelDimension` or `str`, *optional*): + The channel dimension format of the input image. If not provided, it will be inferred. + """ + if "longest_edge" in size: + size = (size["longest_edge"], size["longest_edge"]) + elif "height" in size and "width" in size: + size = (size["height"], size["width"]) + else: + raise ValueError("size must contain either 'longest_edge' or 'height' and 'width'.") + + if "height" in patch_size and "width" in patch_size: + patch_size = (patch_size["height"], patch_size["width"]) + else: + raise ValueError("patch_size must contain either 'shortest_edge' or 'height' and 'width'.") + + output_size = get_resize_output_image_size( + image, + size=size, + patch_size=patch_size, + input_data_format=input_data_format, + ) + return resize( + image, + size=output_size, + resample=resample, + data_format=data_format, + input_data_format=input_data_format, + **kwargs, + ) + + def _pad_for_batching( + self, + pixel_values: list[np.ndarray], + image_sizes: list[list[int]], + data_format: str | ChannelDimension | None = None, + input_data_format: str | ChannelDimension | None = None, + ): + """ + Pads images on the `num_of_patches` dimension with zeros to form a batch of same number of patches. + Args: + pixel_values (`list[np.ndarray]`): + An array of pixel values of each images of shape (`batch_size`, `height`, `width`, `channels`) + image_sizes (`list[list[int]]`): + A list of sizes for each image in `pixel_values` in (height, width) format. + data_format (`str` or `ChannelDimension`, *optional*): + The channel dimension format for the output image. Can be one of: + - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format. + - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format. + If unset, will use same as the input image. + input_data_format (`str` or `ChannelDimension`, *optional*): + The channel dimension format for the input image. Can be one of: + - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format. + - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format. + If unset, will use the inferred format of the input image. + Returns: + list[`np.ndarray`]: The padded images. + """ + + max_shape = ( + max(size[0] for size in image_sizes), + max(size[1] for size in image_sizes), + ) + pixel_values = [ + pad( + image, + padding=((0, max_shape[0] - size[0]), (0, max_shape[1] - size[1])), + data_format=data_format, + input_data_format=input_data_format, + ) + for image, size in zip(pixel_values, image_sizes) + ] + return pixel_values + + def preprocess( + self, + images: ImageInput, + do_resize: bool | None = None, + size: dict[str, int] | None = None, + patch_size: dict[str, int] | None = None, + resample: PILImageResampling | None = None, + do_rescale: bool | None = None, + rescale_factor: float | None = None, + do_normalize: bool | None = None, + image_mean: float | list[float] | None = None, + image_std: float | list[float] | None = None, + do_convert_rgb: bool | None = None, + return_tensors: str | TensorType | None = None, + data_format: ChannelDimension | None = ChannelDimension.FIRST, + input_data_format: str | ChannelDimension | None = None, + **kwargs, + ) -> PIL.Image.Image: + """ + Preprocess an image or batch of images. + + Args: + images (`ImageInput`): + Image to preprocess. Expects a single or batch of images with pixel values ranging from 0 to 255. If + passing in images with pixel values between 0 and 1, set `do_rescale=False`. + do_resize (`bool`, *optional*, defaults to `self.do_resize`): + Whether to resize the image. + size (`dict[str, int]`, *optional*, defaults to `self.size`): + Describes the maximum input dimensions to the model. + patch_size (`dict[str, int]`, *optional*, defaults to `self.patch_size`): + Patch size in the model. Used to calculate the image after resizing. + resample (`int`, *optional*, defaults to `self.resample`): + Resampling filter to use if resizing the image. This can be one of the enum `PILImageResampling`. Only + has an effect if `do_resize` is set to `True`. + do_rescale (`bool`, *optional*, defaults to `self.do_rescale`): + Whether to rescale the image. + rescale_factor (`float`, *optional*, defaults to `self.rescale_factor`): + Rescale factor to rescale the image by if `do_rescale` is set to `True`. + do_normalize (`bool`, *optional*, defaults to `self.do_normalize`): + Whether to normalize the image. + image_mean (`float` or `list[float]`, *optional*, defaults to `self.image_mean`): + Image mean to use for normalization. Only has an effect if `do_normalize` is set to `True`. + image_std (`float` or `list[float]`, *optional*, defaults to `self.image_std`): + Image standard deviation to use for normalization. Only has an effect if `do_normalize` is set to + `True`. + do_convert_rgb (`bool`, *optional*, defaults to `self.do_convert_rgb`): + Whether to convert the image to RGB. + return_tensors (`str` or `TensorType`, *optional*): + The type of tensors to return. Can be one of: + - Unset: Return a list of `np.ndarray`. + - `TensorType.PYTORCH` or `'pt'`: Return a batch of type `torch.Tensor`. + - `TensorType.NUMPY` or `'np'`: Return a batch of type `np.ndarray`. + data_format (`ChannelDimension` or `str`, *optional*, defaults to `ChannelDimension.FIRST`): + The channel dimension format for the output image. Can be one of: + - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format. + - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format. + - Unset: Use the channel dimension format of the input image. + input_data_format (`ChannelDimension` or `str`, *optional*): + The channel dimension format for the input image. If unset, the channel dimension format is inferred + from the input image. Can be one of: + - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format. + - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format. + - `"none"` or `ChannelDimension.NONE`: image in (height, width) format. + """ + patch_size = patch_size if patch_size is not None else self.patch_size + patch_size = get_size_dict(patch_size, default_to_square=True) + + do_resize = do_resize if do_resize is not None else self.do_resize + size = size if size is not None else self.size + resample = resample if resample is not None else self.resample + do_rescale = do_rescale if do_rescale is not None else self.do_rescale + rescale_factor = rescale_factor if rescale_factor is not None else self.rescale_factor + do_normalize = do_normalize if do_normalize is not None else self.do_normalize + image_mean = image_mean if image_mean is not None else self.image_mean + image_std = image_std if image_std is not None else self.image_std + do_convert_rgb = do_convert_rgb if do_convert_rgb is not None else self.do_convert_rgb + + validate_kwargs(captured_kwargs=kwargs.keys(), valid_processor_keys=self._valid_processor_keys) + + images = self.fetch_images(images) + images = make_flat_list_of_images(images) + + if not valid_images(images[0]): + raise ValueError("Invalid image type. Must be of type PIL.Image.Image, numpy.ndarray, or torch.Tensor") + + validate_preprocess_arguments( + do_rescale=do_rescale, + rescale_factor=rescale_factor, + do_normalize=do_normalize, + image_mean=image_mean, + image_std=image_std, + do_resize=do_resize, + size=size, + resample=resample, + ) + + if do_convert_rgb: + images = [convert_to_rgb(image) for image in images] + + # All transformations expect numpy arrays. + images = [to_numpy_array(image) for image in images] + + if do_rescale and is_scaled_image(images[0]): + logger.warning_once( + "It looks like you are trying to rescale already rescaled images. If the input" + " images have pixel values between 0 and 1, set `do_rescale=False` to avoid rescaling them again." + ) + + if input_data_format is None: + # We assume that all images have the same channel dimension format. + input_data_format = infer_channel_dimension_format(images[0]) + + batch_images = [] + batch_image_sizes = [] + for image in images: + if do_resize: + image = self.resize( + image=image, + size=size, + patch_size=patch_size, + resample=resample, + input_data_format=input_data_format, + ) + + if do_rescale: + image = self.rescale(image=image, scale=rescale_factor, input_data_format=input_data_format) + + if do_normalize: + image = self.normalize( + image=image, mean=image_mean, std=image_std, input_data_format=input_data_format + ) + + image = to_channel_dimension_format(image, data_format, input_channel_dim=input_data_format) + + batch_images.append(image) + batch_image_sizes.append(get_image_size(image, data_format)) + + pixel_values = self._pad_for_batching( + pixel_values=batch_images, + image_sizes=batch_image_sizes, + input_data_format=data_format, + data_format=data_format, + ) + + return BatchFeature( + data={"pixel_values": pixel_values, "image_sizes": batch_image_sizes}, tensor_type=return_tensors + ) + + +__all__ = ["PixtralImageProcessor"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pixtral/image_processing_pixtral_fast.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pixtral/image_processing_pixtral_fast.py new file mode 100644 index 0000000000000000000000000000000000000000..247f7dee6232942a747bc9b137f169797735c980 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pixtral/image_processing_pixtral_fast.py @@ -0,0 +1,181 @@ +# Copyright 2024 The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""Image processor class for Pixtral.""" + +from typing import Optional + +import torch +import torchvision.transforms.v2.functional as tvF + +from ...image_processing_utils import BatchFeature, get_size_dict +from ...image_processing_utils_fast import ( + BaseImageProcessorFast, + group_images_by_shape, + reorder_images, +) +from ...image_utils import ImageInput, PILImageResampling, SizeDict +from ...processing_utils import Unpack +from ...utils import ( + TensorType, + auto_docstring, + logging, +) +from .image_processing_pixtral import PixtralImageProcessorKwargs, get_resize_output_image_size + + +logger = logging.get_logger(__name__) + + +@auto_docstring +class PixtralImageProcessorFast(BaseImageProcessorFast): + resample = PILImageResampling.BICUBIC + image_mean = [0.48145466, 0.4578275, 0.40821073] + image_std = [0.26862954, 0.26130258, 0.27577711] + patch_size = {"height": 16, "width": 16} + size = {"longest_edge": 1024} + default_to_square = True + do_resize = True + do_rescale = True + do_normalize = True + do_convert_rgb = True + valid_kwargs = PixtralImageProcessorKwargs + + model_input_names = ["pixel_values", "image_sizes"] + + def __init__(self, **kwargs: Unpack[PixtralImageProcessorKwargs]): + super().__init__(**kwargs) + + @auto_docstring + def preprocess(self, images: ImageInput, **kwargs: Unpack[PixtralImageProcessorKwargs]) -> BatchFeature: + return super().preprocess(images, **kwargs) + + def resize( + self, + image: torch.Tensor, + size: SizeDict, + patch_size: SizeDict, + interpolation: Optional["tvF.InterpolationMode"] = None, + **kwargs, + ) -> torch.Tensor: + """ + Resize an image. The shortest edge of the image is resized to size["shortest_edge"], with the longest edge + resized to keep the input aspect ratio. + + Args: + image (`torch.Tensor`): + Image to resize. + size (`SizeDict`): + Dict containing the longest possible edge of the image. + patch_size (`SizeDict`): + Patch size used to calculate the size of the output image. + interpolation (`InterpolationMode`, *optional*, defaults to `InterpolationMode.BILINEAR`): + Resampling filter to use when resiizing the image. + """ + interpolation = interpolation if interpolation is not None else tvF.InterpolationMode.BILINEAR + if size.longest_edge: + size = (size.longest_edge, size.longest_edge) + elif size.height and size.width: + size = (size.height, size.width) + else: + raise ValueError("size must contain either 'longest_edge' or 'height' and 'width'.") + + if patch_size.height and patch_size.width: + patch_size = (patch_size.height, patch_size.width) + else: + raise ValueError("patch_size must contain either 'shortest_edge' or 'height' and 'width'.") + + output_size = get_resize_output_image_size(image, size=size, patch_size=patch_size) + return tvF.resize(image, size=output_size, interpolation=interpolation, **kwargs) + + # Adapted from transformers.models.pixtral.image_processing_pixtral.PixtralImageProcessor._pad_for_batching + def _pad_for_batching( + self, + pixel_values: list[torch.Tensor], + image_sizes: list[list[int]], + ): + """ + Pads images on the `num_of_patches` dimension with zeros to form a batch of same number of patches. + Args: + pixel_values (`list[torch.Tensor]`): + An array of pixel values of each images of shape (`batch_size`, `channels`, `height`, `width`) + image_sizes (`list[list[int]]`): + A list of sizes for each image in `pixel_values` in (height, width) format. + Returns: + list[`torch.Tensor`]: The padded images. + """ + + max_shape = (max(size[0] for size in image_sizes), max(size[1] for size in image_sizes)) + pixel_values = [ + torch.nn.functional.pad(image, pad=(0, max_shape[1] - size[1], 0, max_shape[0] - size[0])) + for image, size in zip(pixel_values, image_sizes) + ] + return torch.stack(pixel_values) + + def _preprocess( + self, + images: list["torch.Tensor"], + do_resize: bool, + size: SizeDict, + patch_size: dict[str, int], + interpolation: Optional["tvF.InterpolationMode"], + do_center_crop: bool, + crop_size: dict[str, int], + do_rescale: bool, + rescale_factor: float, + do_normalize: bool, + image_mean: float | list[float] | None, + image_std: float | list[float] | None, + disable_grouping: bool | None, + return_tensors: str | TensorType | None, + **kwargs, + ) -> BatchFeature: + patch_size = get_size_dict(patch_size, default_to_square=True) + patch_size = SizeDict(**patch_size) + # Group images by size for batched resizing + grouped_images, grouped_images_index = group_images_by_shape(images, disable_grouping=disable_grouping) + resized_images_grouped = {} + for shape, stacked_images in grouped_images.items(): + if do_resize: + stacked_images = self.resize( + image=stacked_images, size=size, patch_size=patch_size, interpolation=interpolation + ) + resized_images_grouped[shape] = stacked_images + resized_images = reorder_images(resized_images_grouped, grouped_images_index) + + # Group images by size for further processing + # Needed in case do_resize is False, or resize returns images with different sizes + grouped_images, grouped_images_index = group_images_by_shape(resized_images, disable_grouping=disable_grouping) + batch_image_sizes = [grouped_images_index[i][0] for i in range(len(grouped_images_index))] + processed_images_grouped = {} + for shape, stacked_images in grouped_images.items(): + if do_center_crop: + stacked_images = self.center_crop(stacked_images, crop_size) + # Fused rescale and normalize + stacked_images = self.rescale_and_normalize( + stacked_images, do_rescale, rescale_factor, do_normalize, image_mean, image_std + ) + processed_images_grouped[shape] = stacked_images + + processed_images = reorder_images(processed_images_grouped, grouped_images_index) + padded_images = self._pad_for_batching( + pixel_values=processed_images, + image_sizes=batch_image_sizes, + ) + + return BatchFeature( + data={"pixel_values": padded_images, "image_sizes": batch_image_sizes}, tensor_type=return_tensors + ) + + +__all__ = ["PixtralImageProcessorFast"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pixtral/modeling_pixtral.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pixtral/modeling_pixtral.py new file mode 100644 index 0000000000000000000000000000000000000000..7558dafca6d006e3331f385ace859a2f850f41d5 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pixtral/modeling_pixtral.py @@ -0,0 +1,534 @@ +# Copyright 2024 Mistral and the HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""PyTorch Pixtral model.""" + +from collections.abc import Callable +from typing import Optional + +import torch +from torch import nn + +from ...activations import ACT2FN +from ...modeling_flash_attention_utils import FlashAttentionKwargs +from ...modeling_layers import GradientCheckpointingLayer +from ...modeling_outputs import BaseModelOutput +from ...modeling_rope_utils import dynamic_rope_update +from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel +from ...processing_utils import Unpack +from ...utils import auto_docstring, can_return_tuple, logging +from ...utils.generic import is_flash_attention_requested, maybe_autocast +from .configuration_pixtral import PixtralVisionConfig + + +logger = logging.get_logger(__name__) + + +def position_ids_in_meshgrid(patch_embeds_list, max_width): + positions = [] + for patch in patch_embeds_list: + height, width = patch.shape[-2:] + mesh = torch.meshgrid(torch.arange(height), torch.arange(width), indexing="ij") + h_grid, v_grid = torch.stack(mesh, dim=-1).reshape(-1, 2).chunk(2, -1) + ids = h_grid * max_width + v_grid + positions.append(ids[:, 0]) + return torch.cat(positions) + + +class PixtralRotaryEmbedding(nn.Module): + """ + The key with pixtral embedding is just that you have a frequency for each pixel positions. + If you have height x width pixels (or embedding pixels), then the frequency used for ROPE + is given by indexing the pre_computed frequency on the width and height. + + What you output is of dimension (batch, height * width, dim) with dim the embed dim. + + This simply means that for each image hidden state, you are going to add + a corresponding positional embedding, based on its index in the grid. + """ + + inv_freq: torch.Tensor # fix linting for `register_buffer` + + def __init__(self, config: PixtralVisionConfig, device=None, layer_type=None): + super().__init__() + + self.config = config + + self.rope_type = self.config.rope_parameters["rope_type"] + rope_init_fn: Callable = self.compute_default_rope_parameters + if self.rope_type != "default": + raise ValueError( + f"{self.__class__.__name__} does not support non-default RoPE, but got `rope_type={self.rope_type}`" + ) + + inv_freq, attention_scaling = rope_init_fn(self.config, device) + self.register_buffer("inv_freq", inv_freq, persistent=False) + self.register_buffer("original_inv_freq", inv_freq.clone(), persistent=False) + + @staticmethod + def compute_default_rope_parameters( + config: PixtralVisionConfig | None = None, + device: Optional["torch.device"] = None, + seq_len: int | None = None, + ) -> tuple["torch.Tensor", float]: + """ + Computes the inverse frequencies according to the original RoPE implementation + Args: + config ([`~transformers.PreTrainedConfig`]): + The model configuration. + device (`torch.device`): + The device to use for initialization of the inverse frequencies. + seq_len (`int`, *optional*): + The current sequence length. Unused for this type of RoPE. + Returns: + Tuple of (`torch.Tensor`, `float`), containing the inverse frequencies for the RoPE embeddings and the + post-processing scaling factor applied to the computed cos/sin (unused in this type of RoPE). + """ + base = config.rope_parameters["rope_theta"] + dim = getattr(config, "head_dim", None) or config.hidden_size // config.num_attention_heads + + attention_factor = 1.0 # Unused in this type of RoPE + + # Here is the diff from Llama RoPE + max_patches_per_side = config.image_size // config.patch_size + h = torch.arange(max_patches_per_side) + w = torch.arange(max_patches_per_side) + + freqs = 1.0 / (base ** (torch.arange(0, dim, 2).float() / dim)) + freqs_h = torch.outer(h, freqs[::2]).float() + freqs_w = torch.outer(w, freqs[1::2]).float() + inv_freq = torch.cat( + [ + freqs_h[:, None, :].repeat(1, max_patches_per_side, 1), + freqs_w[None, :, :].repeat(max_patches_per_side, 1, 1), + ], + dim=-1, + ).reshape(-1, dim // 2) # we reshape to only index on the position indexes, not tuple of indexes + # Different from paper, but it uses a different permutation in order to obtain the same calculation + + # TODO maybe make it torch compatible later on. We can also just slice + inv_freq = torch.cat((inv_freq, inv_freq), dim=-1) + return inv_freq, attention_factor + + @torch.no_grad() + @dynamic_rope_update # power user: used with advanced RoPE types (e.g. dynamic rope) + def forward(self, x, position_ids): + freqs = self.inv_freq[position_ids] + device_type = x.device.type if isinstance(x.device.type, str) and x.device.type != "mps" else "cpu" + with maybe_autocast(device_type=device_type, enabled=False): # Force float32 + emb = freqs + cos = emb.cos() + sin = emb.sin() + + return cos.to(dtype=x.dtype), sin.to(dtype=x.dtype) + + +# Copied from transformers.models.llama.modeling_llama.rotate_half +def rotate_half(x): + """Rotates half the hidden dims of the input.""" + x1 = x[..., : x.shape[-1] // 2] + x2 = x[..., x.shape[-1] // 2 :] + return torch.cat((-x2, x1), dim=-1) + + +def apply_rotary_pos_emb(q, k, cos, sin, unsqueeze_dim=1): + """Applies Rotary Position Embedding to the query and key tensors. + + Args: + q (`torch.Tensor`): The query tensor. + k (`torch.Tensor`): The key tensor. + cos (`torch.Tensor`): The cosine part of the rotary embedding. + sin (`torch.Tensor`): The sine part of the rotary embedding. + unsqueeze_dim (`int`, *optional*, defaults to 1): + The 'unsqueeze_dim' argument specifies the dimension along which to unsqueeze cos[position_ids] and + sin[position_ids] so that they can be properly broadcasted to the dimensions of q and k. For example, note + that cos[position_ids] and sin[position_ids] have the shape [batch_size, seq_len, head_dim]. Then, if q and + k have the shape [batch_size, heads, seq_len, head_dim], then setting unsqueeze_dim=1 makes + cos[position_ids] and sin[position_ids] broadcastable to the shapes of q and k. Similarly, if q and k have + the shape [batch_size, seq_len, heads, head_dim], then set unsqueeze_dim=2. + Returns: + `tuple(torch.Tensor)` comprising of the query and key tensors rotated using the Rotary Position Embedding. + """ + cos = cos.unsqueeze(unsqueeze_dim) + sin = sin.unsqueeze(unsqueeze_dim) + q_embed = (q * cos) + (rotate_half(q) * sin) + k_embed = (k * cos) + (rotate_half(k) * sin) + return q_embed, k_embed + + +# Copied from transformers.models.siglip.modeling_siglip.eager_attention_forward +def eager_attention_forward( + module: nn.Module, + query: torch.Tensor, + key: torch.Tensor, + value: torch.Tensor, + attention_mask: torch.Tensor | None, + scaling: float, + dropout: float = 0.0, + **kwargs, +): + attn_weights = torch.matmul(query, key.transpose(-1, -2)) * scaling + if attention_mask is not None: + attn_weights = attn_weights + attention_mask + + attn_weights = nn.functional.softmax(attn_weights, dim=-1, dtype=torch.float32).to(query.dtype) + attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training) + + attn_output = torch.matmul(attn_weights, value) + attn_output = attn_output.transpose(1, 2).contiguous() + + return attn_output, attn_weights + + +class PixtralAttention(nn.Module): + """ + Multi-headed attention compatible with ALL_ATTENTION_FUNCTIONS. + """ + + def __init__(self, config): + super().__init__() + self.config = config + self.embed_dim = config.hidden_size + self.num_heads = config.num_attention_heads + self.head_dim = self.embed_dim // self.num_heads + self.is_causal = False + + self.scaling = self.head_dim**-0.5 + self.is_causal = False + + self.dropout = config.attention_dropout + + self.k_proj = nn.Linear(self.embed_dim, self.embed_dim, bias=False) + self.v_proj = nn.Linear(self.embed_dim, self.embed_dim, bias=False) + self.q_proj = nn.Linear(self.embed_dim, self.embed_dim, bias=False) + self.o_proj = nn.Linear(self.embed_dim, self.embed_dim, bias=False) + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.Tensor | None = None, + position_embeddings: tuple[torch.Tensor, torch.Tensor] | None = None, + output_attentions: bool | None = False, + **kwargs: Unpack[FlashAttentionKwargs], + ) -> tuple[torch.Tensor, torch.Tensor | None]: + """Input shape: Batch x Time x Channel""" + + batch_size, patches, _ = hidden_states.size() + + query_states = self.q_proj(hidden_states) + key_states = self.k_proj(hidden_states) + value_states = self.v_proj(hidden_states) + + query_states = query_states.view(batch_size, patches, self.num_heads, self.head_dim).transpose(1, 2) + key_states = key_states.view(batch_size, patches, self.num_heads, self.head_dim).transpose(1, 2) + value_states = value_states.view(batch_size, patches, self.num_heads, self.head_dim).transpose(1, 2) + + cos, sin = position_embeddings + query_states, key_states = apply_rotary_pos_emb(query_states, key_states, cos, sin, unsqueeze_dim=0) + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, eager_attention_forward + ) + + attn_output, attn_weights = attention_interface( + self, + query_states, + key_states, + value_states, + attention_mask, + dropout=0.0 if not self.training else self.dropout, + scaling=self.scaling, + **kwargs, + ) + + attn_output = attn_output.reshape(batch_size, patches, -1).contiguous() + attn_output = self.o_proj(attn_output) + + if not output_attentions: + attn_weights = None + return attn_output, attn_weights + + +# Copied from transformers.models.mistral.modeling_mistral.MistralMLP with Mistral->Pixtral +class PixtralMLP(nn.Module): + def __init__(self, config): + super().__init__() + self.config = config + self.hidden_size = config.hidden_size + self.intermediate_size = config.intermediate_size + self.gate_proj = nn.Linear(self.hidden_size, self.intermediate_size, bias=False) + self.up_proj = nn.Linear(self.hidden_size, self.intermediate_size, bias=False) + self.down_proj = nn.Linear(self.intermediate_size, self.hidden_size, bias=False) + self.act_fn = ACT2FN[config.hidden_act] + + def forward(self, x): + down_proj = self.down_proj(self.act_fn(self.gate_proj(x)) * self.up_proj(x)) + return down_proj + + +# Copied from transformers.models.llama.modeling_llama.LlamaRMSNorm with Llama->Pixtral +class PixtralRMSNorm(nn.Module): + def __init__(self, hidden_size, eps: float = 1e-6) -> None: + """ + PixtralRMSNorm is equivalent to T5LayerNorm + """ + super().__init__() + self.weight = nn.Parameter(torch.ones(hidden_size)) + self.variance_epsilon = eps + + def forward(self, hidden_states: torch.Tensor) -> torch.Tensor: + input_dtype = hidden_states.dtype + hidden_states = hidden_states.to(torch.float32) + variance = hidden_states.pow(2).mean(-1, keepdim=True) + hidden_states = hidden_states * torch.rsqrt(variance + self.variance_epsilon) + return self.weight * hidden_states.to(input_dtype) + + def extra_repr(self): + return f"{tuple(self.weight.shape)}, eps={self.variance_epsilon}" + + +class PixtralAttentionLayer(GradientCheckpointingLayer): + def __init__(self, config): + super().__init__() + self.attention_norm = PixtralRMSNorm(config.hidden_size, eps=1e-5) + self.feed_forward = PixtralMLP(config) + self.attention = PixtralAttention(config) + self.ffn_norm = PixtralRMSNorm(config.hidden_size, eps=1e-5) + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.Tensor, + position_embeddings: tuple[torch.Tensor, torch.Tensor] | None = None, + output_attentions: bool | None = None, + **kwargs: Unpack[FlashAttentionKwargs], + ) -> tuple[torch.FloatTensor]: + """ + Args: + hidden_states (`torch.FloatTensor`): + Input to the layer of shape `(batch, seq_len, embed_dim)`. + attention_mask (`torch.FloatTensor`): + Attention mask of shape `(batch, 1, q_len, k_v_seq_len)` where padding elements are indicated by very large negative values. + output_attentions (`bool`, *optional*, defaults to `False`): + Whether or not to return the attentions tensors of all attention layers. See `attentions` under + returned tensors for more detail. + """ + residual = hidden_states + + hidden_states = self.attention_norm(hidden_states) + hidden_states, attn_weights = self.attention( + hidden_states=hidden_states, + attention_mask=attention_mask, + position_embeddings=position_embeddings, + output_attentions=output_attentions, + **kwargs, + ) + hidden_states = residual + hidden_states + + residual = hidden_states + hidden_states = self.ffn_norm(hidden_states) + hidden_states = self.feed_forward(hidden_states) + hidden_states = residual + hidden_states + + outputs = (hidden_states,) + + if output_attentions: + outputs += (attn_weights,) + return outputs + + +class PixtralTransformer(nn.Module): + def __init__(self, config): + super().__init__() + self.config = config + self.layers = torch.nn.ModuleList() + for _ in range(config.num_hidden_layers): + self.layers.append(PixtralAttentionLayer(config)) + self.gradient_checkpointing = False + + def forward( + self, + inputs_embeds, + attention_mask: torch.Tensor | None = None, + position_embeddings: tuple[torch.Tensor, torch.Tensor] | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + **kwargs: Unpack[FlashAttentionKwargs], + ) -> tuple | BaseModelOutput: + r""" + Args: + inputs_embeds (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`): + Embeddings which serve as input to the Transformer. + attention_mask (`torch.Tensor` of shape `(batch_size, sequence_length)`, *optional*): + Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`: + + - 1 for tokens that are **not masked**, + - 0 for tokens that are **masked**. + + [What are attention masks?](../glossary#attention-mask) + output_attentions (`bool`, *optional*): + Whether or not to return the attentions tensors of all attention layers. See `attentions` under + returned tensors for more detail. + output_hidden_states (`bool`, *optional*): + Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors + for more detail. + return_dict (`bool`, *optional*): + Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple. + """ + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + encoder_states = () if output_hidden_states else None + all_attentions = () if output_attentions else None + + hidden_states = inputs_embeds + for encoder_layer in self.layers: + if output_hidden_states: + encoder_states = encoder_states + (hidden_states,) + layer_outputs = encoder_layer( + hidden_states, + attention_mask, + position_embeddings=position_embeddings, + output_attentions=output_attentions, + **kwargs, + ) + + hidden_states = layer_outputs[0] + + if output_attentions: + all_attentions = all_attentions + (layer_outputs[1],) + + if output_hidden_states: + encoder_states = encoder_states + (hidden_states,) + + if not return_dict: + return tuple(v for v in [hidden_states, encoder_states, all_attentions] if v is not None) + return BaseModelOutput( + last_hidden_state=hidden_states, hidden_states=encoder_states, attentions=all_attentions + ) + + +@auto_docstring +class PixtralPreTrainedModel(PreTrainedModel): + config: PixtralVisionConfig + base_model_prefix = "model" + main_input_name = "pixel_values" + input_modalities = ("image",) + supports_gradient_checkpointing = True + _supports_attention_backend = True + _supports_flash_attn = True + _supports_sdpa = True + _supports_flex_attn = True + _no_split_modules = ["PixtralAttentionLayer"] + + +def generate_block_attention_mask(patch_embeds_list, tensor): + dtype = tensor.dtype + device = tensor.device + seq_len = tensor.shape[1] + d_min = torch.finfo(dtype).min + causal_mask = torch.full((seq_len, seq_len), fill_value=d_min, dtype=dtype, device=device) + + block_end_idx = torch.tensor(patch_embeds_list).cumsum(-1) + block_start_idx = torch.tensor([0] + patch_embeds_list[:-1]).cumsum(-1) + for start, end in zip(block_start_idx, block_end_idx): + causal_mask[start:end, start:end] = 0 + + causal_mask = causal_mask[None, None, :, :].expand(tensor.shape[0], 1, -1, -1) + return causal_mask + + +@auto_docstring +class PixtralVisionModel(PixtralPreTrainedModel): + base_model_prefix = "vision_encoder" + + def __init__(self, config): + super().__init__(config) + self.config = config + self.patch_conv = nn.Conv2d( + in_channels=config.num_channels, + out_channels=config.hidden_size, + kernel_size=config.patch_size, + stride=config.patch_size, + bias=False, + ) + self.patch_size = config.patch_size + self.ln_pre = PixtralRMSNorm(config.hidden_size, eps=1e-5) + self.transformer = PixtralTransformer(config) + self.patch_positional_embedding = PixtralRotaryEmbedding(config) + + self.post_init() + + def get_input_embeddings(self): + return self.patch_conv + + @can_return_tuple + @auto_docstring + def forward( + self, + pixel_values: torch.Tensor, + image_sizes: torch.Tensor | None = None, + output_hidden_states: bool | None = None, + output_attentions: bool | None = None, + return_dict: bool | None = None, + *args, + **kwargs: Unpack[FlashAttentionKwargs], + ) -> tuple | BaseModelOutput: + if image_sizes is None: + batch_size, _, height, width = pixel_values.shape + image_sizes = [(height, width)] * batch_size + + # pass images through initial convolution independently + target_dtype = self.patch_conv.weight.dtype + patch_embeds = self.patch_conv(pixel_values.to(dtype=target_dtype)) + patch_embeds_list = [ + embed[..., : (size[0] // self.patch_size), : (size[1] // self.patch_size)] + for embed, size in zip(patch_embeds, image_sizes) + ] + + # flatten to a single sequence + patch_embeds = torch.cat([p.flatten(1).T for p in patch_embeds_list], dim=0).unsqueeze(0) + patch_embeds = self.ln_pre(patch_embeds) + + # positional embeddings + position_ids = position_ids_in_meshgrid( + patch_embeds_list, max_width=self.config.image_size // self.config.patch_size + ) + kwargs["position_ids"] = position_ids.unsqueeze(0).to(patch_embeds.device, non_blocking=True) + + position_embeddings = self.patch_positional_embedding(patch_embeds, position_ids) + + if is_flash_attention_requested(self.config): + # We only rely on position_ids when using flash attention + attention_mask = None + else: + attention_mask = generate_block_attention_mask( + [p.shape[-2] * p.shape[-1] for p in patch_embeds_list], patch_embeds + ) + + return self.transformer( + patch_embeds, + attention_mask=attention_mask, + position_embeddings=position_embeddings, + output_hidden_states=output_hidden_states, + output_attentions=output_attentions, + return_dict=True, + **kwargs, + ) + + +__all__ = ["PixtralVisionModel", "PixtralPreTrainedModel"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pixtral/processing_pixtral.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pixtral/processing_pixtral.py new file mode 100644 index 0000000000000000000000000000000000000000..569a73cf681d144294bbc3e18f4522f959264b10 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pixtral/processing_pixtral.py @@ -0,0 +1,222 @@ +# Copyright 2024 The HuggingFace Inc. team. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +""" +Processor class for Pixtral. +""" + +import numpy as np + +from ...feature_extraction_utils import BatchFeature +from ...image_utils import ImageInput, is_valid_image +from ...processing_utils import ( + MultiModalData, + ProcessingKwargs, + ProcessorMixin, + Unpack, +) +from ...tokenization_utils_base import PreTokenizedInput, TextInput +from ...utils import auto_docstring, is_vision_available, logging + + +if is_vision_available(): + from .image_processing_pixtral import get_resize_output_image_size + + +logger = logging.get_logger(__name__) + + +class PixtralProcessorKwargs(ProcessingKwargs, total=False): + _defaults = { + "text_kwargs": { + "padding": False, + "return_mm_token_type_ids": False, + }, + "common_kwargs": { + "return_tensors": "pt", + }, + } + + +# Copied from transformers.models.idefics2.processing_idefics2.is_url +def is_url(val) -> bool: + return isinstance(val, str) and val.startswith("http") + + +# Copied from transformers.models.idefics2.processing_idefics2.is_image_or_image_url +def is_image_or_image_url(elem): + return is_url(elem) or is_valid_image(elem) + + +@auto_docstring +class PixtralProcessor(ProcessorMixin): + def __init__( + self, + image_processor=None, + tokenizer=None, + patch_size: int = 16, + spatial_merge_size: int = 1, + chat_template=None, + image_token="[IMG]", # set the default and let users change if they have peculiar special tokens in rare cases + image_break_token="[IMG_BREAK]", + image_end_token="[IMG_END]", + **kwargs, + ): + r""" + patch_size (`int`, *optional*, defaults to 16): + Patch size from the vision tower. + spatial_merge_size (`int`, *optional*, defaults to 1): + The downsampling factor for the spatial merge operation. + image_token (`str`, *optional*, defaults to `"[IMG]"`): + Special token used to denote image location. + image_break_token (`str`, *optional*, defaults to `"[IMG_BREAK]"`): + Special token used to denote the end of a line of pixels in an image. + image_end_token (`str`, *optional*, defaults to `"[IMG_END]"`): + Special token used to denote the end of an image input. + """ + self.patch_size = patch_size + self.spatial_merge_size = spatial_merge_size + self.image_token = image_token + self.image_token_id = tokenizer.convert_tokens_to_ids(self.image_token) + self.image_break_token = image_break_token + self.image_end_token = image_end_token + self.image_token_id = tokenizer.convert_tokens_to_ids(self.image_token) + self.image_break_token_id = tokenizer.convert_tokens_to_ids(self.image_break_token) + self.image_end_token_id = tokenizer.convert_tokens_to_ids(self.image_end_token) + self.image_ids = [self.image_token_id, self.image_break_token_id, self.image_end_token_id] + super().__init__(image_processor, tokenizer, chat_template=chat_template) + + @auto_docstring + def __call__( + self, + images: ImageInput | None = None, + text: TextInput | PreTokenizedInput | list[TextInput] | list[PreTokenizedInput] = None, + **kwargs: Unpack[PixtralProcessorKwargs], + ) -> BatchFeature: + r""" + Returns: + [`BatchFeature`]: A [`BatchFeature`] with the following fields: + + - **input_ids** -- List of token ids to be fed to a model. Returned when `text` is not `None`. + - **attention_mask** -- List of indices specifying which tokens should be attended to by the model (when + `return_attention_mask=True` or if *"attention_mask"* is in `self.model_input_names` and if `text` is not + `None`). + - **pixel_values** -- Pixel values to be fed to a model. Returned when `images` is not `None`. + """ + + output_kwargs = self._merge_kwargs( + PixtralProcessorKwargs, + tokenizer_init_kwargs=getattr(self.tokenizer, "init_kwargs", {}), + **kwargs, + ) + + patch_size = self.patch_size * self.spatial_merge_size + + if images is not None: + output_kwargs["images_kwargs"]["patch_size"] = patch_size + image_inputs = self.image_processor(images, **output_kwargs["images_kwargs"]) + else: + image_inputs = {} + + if isinstance(text, str): + text = [text] + elif not isinstance(text, list) and not isinstance(text[0], str): + raise TypeError("Invalid input text. Please provide a string, or a list of strings") + + # try to expand inputs in processing if we have the necessary parts + prompt_strings = text + if image_inputs.get("pixel_values") is not None: + # Replace the image token with the expanded image token sequence + image_sizes = iter(image_inputs["image_sizes"]) + prompt_strings = [] + replace_strings = [] + + for sample in text: + while self.image_token in sample: + height, width = next(image_sizes) + num_height_tokens = height // patch_size + num_width_tokens = width // patch_size + replace_tokens = [ + [self.image_token] * num_width_tokens + [self.image_break_token] + ] * num_height_tokens + # Flatten list + replace_tokens = [item for sublist in replace_tokens for item in sublist] + replace_tokens[-1] = self.image_end_token + replace_str = "".join(replace_tokens) + replace_strings.append(replace_str) + sample = sample.replace(self.image_token, "", 1) + + while "" in sample: + replace_str = replace_strings.pop(0) + sample = sample.replace("", replace_str, 1) + prompt_strings.append(sample) + + return_tensors = output_kwargs["text_kwargs"].pop("return_tensors", None) + return_mm_token_type_ids = output_kwargs["text_kwargs"].pop("return_mm_token_type_ids", False) + # Remove return_token_type_ids as MistralCommonBackend doesn't support it + output_kwargs["text_kwargs"].pop("return_token_type_ids", None) + text_inputs = self.tokenizer(prompt_strings, **output_kwargs["text_kwargs"], return_tensors=None) + self._check_special_mm_tokens(prompt_strings, text_inputs, modalities=["image"]) + + if return_mm_token_type_ids: + array_ids = np.array(text_inputs["input_ids"]) + mm_token_type_ids = np.zeros_like(text_inputs["input_ids"]) + mm_token_type_ids[np.isin(array_ids, self.image_ids)] = 1 + text_inputs["mm_token_type_ids"] = mm_token_type_ids.tolist() + + return BatchFeature(data={**text_inputs, **image_inputs}, tensor_type=return_tensors) + + def _get_num_multimodal_tokens(self, image_sizes=None, **kwargs): + """ + Computes the number of placeholder tokens needed for multimodal inputs with the given sizes. + + Args: + image_sizes (`list[list[int]]`, *optional*): + The input sizes formatted as (height, width) per each image. + + Returns: + `MultiModalData`: A `MultiModalData` object holding number of tokens per each of the provided + input modalities, along with other useful data. + """ + vision_data = {} + if image_sizes is not None: + images_kwargs = PixtralProcessorKwargs._defaults.get("images_kwargs", {}) + images_kwargs.update(kwargs) + + size = images_kwargs.get("size", None) or self.image_processor.size + patch_size = self.patch_size * self.spatial_merge_size + + num_image_tokens = [] + for height, width in image_sizes: + resized_height, resized_width = get_resize_output_image_size( + np.zeros((height, width, 3)), + size=(size["longest_edge"], size["longest_edge"]), + patch_size=(patch_size, patch_size), + ) + num_height_tokens = resized_height // patch_size + num_width_tokens = resized_width // patch_size + num_image_tokens.append((num_width_tokens + 1) * num_height_tokens) + + num_image_patches = [1] * len(image_sizes) + vision_data.update({"num_image_tokens": num_image_tokens, "num_image_patches": num_image_patches}) + + return MultiModalData(**vision_data) + + @property + def model_input_names(self): + tokenizer_input_names = self.tokenizer.model_input_names + image_processor_input_names = self.image_processor.model_input_names + return tokenizer_input_names + image_processor_input_names + ["image_sizes"] + + +__all__ = ["PixtralProcessor"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/plbart/__init__.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/plbart/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..33e5618ca7e1727c0ce28458d952ce0bfbbfee59 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/plbart/__init__.py @@ -0,0 +1,28 @@ +# Copyright 2024 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from typing import TYPE_CHECKING + +from ...utils import _LazyModule +from ...utils.import_utils import define_import_structure + + +if TYPE_CHECKING: + from .configuration_plbart import * + from .modeling_plbart import * + from .tokenization_plbart import * +else: + import sys + + _file = globals()["__file__"] + sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__) diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/plbart/configuration_plbart.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/plbart/configuration_plbart.py new file mode 100644 index 0000000000000000000000000000000000000000..fde90f8431c63dc6c8eccd068d8deae0b9eaed4e --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/plbart/configuration_plbart.py @@ -0,0 +1,167 @@ +# Copyright 2022, UCLA NLP, The Facebook AI Research Team and The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""PLBART model configuration""" + +from ...configuration_utils import PreTrainedConfig +from ...utils import logging + + +logger = logging.get_logger(__name__) + + +class PLBartConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`PLBartModel`]. It is used to instantiate an + PLBART model according to the specified arguments, defining the model architecture. Instantiating a configuration + with the defaults will yield a similar configuration to that of the PLBART + [uclanlp/plbart-base](https://huggingface.co/uclanlp/plbart-base) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + + Args: + vocab_size (`int`, *optional*, defaults to 50005): + Vocabulary size of the PLBART model. Defines the number of different tokens that can be represented by the + `inputs_ids` passed when calling [`PLBartModel`]. + d_model (`int`, *optional*, defaults to 768): + Dimensionality of the layers and the pooler layer. + encoder_layers (`int`, *optional*, defaults to 6): + Number of encoder layers. + decoder_layers (`int`, *optional*, defaults to 6): + Number of decoder layers. + encoder_attention_heads (`int`, *optional*, defaults to 12): + Number of attention heads for each attention layer in the Transformer encoder. + decoder_attention_heads (`int`, *optional*, defaults to 12): + Number of attention heads for each attention layer in the Transformer decoder. + decoder_ffn_dim (`int`, *optional*, defaults to 3072): + Dimensionality of the "intermediate" (often named feed-forward) layer in decoder. + encoder_ffn_dim (`int`, *optional*, defaults to 3072): + Dimensionality of the "intermediate" (often named feed-forward) layer in decoder. + activation_function (`str` or `function`, *optional*, defaults to `"gelu"`): + The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`, + `"relu"`, `"silu"` and `"gelu_new"` are supported. + dropout (`float`, *optional*, defaults to 0.1): + The dropout probability for all fully connected layers in the embeddings, encoder, and pooler. + attention_dropout (`float`, *optional*, defaults to 0.1): + The dropout ratio for the attention probabilities. + activation_dropout (`float`, *optional*, defaults to 0.0): + The dropout ratio for activations inside the fully connected layer. + classifier_dropout (`float`, *optional*, defaults to 0.0): + The dropout ratio for classifier. + max_position_embeddings (`int`, *optional*, defaults to 1024): + The maximum sequence length that this model might ever be used with. Typically set this to something large + just in case (e.g., 512 or 1024 or 2048). + init_std (`float`, *optional*, defaults to 0.02): + The standard deviation of the truncated_normal_initializer for initializing all weight matrices. + encoder_layerdrop (`float`, *optional*, defaults to 0.0): + The LayerDrop probability for the encoder. See the [LayerDrop paper](see https://huggingface.co/papers/1909.11556) + for more details. + decoder_layerdrop (`float`, *optional*, defaults to 0.0): + The LayerDrop probability for the decoder. See the [LayerDrop paper](see https://huggingface.co/papers/1909.11556) + for more details. + scale_embedding (`bool`, *optional*, defaults to `True`): + Scale embeddings by diving by sqrt(d_model). + use_cache (`bool`, *optional*, defaults to `True`): + Whether or not the model should return the last key/values attentions (not used by all models) + forced_eos_token_id (`int`, *optional*, defaults to 2): + The id of the token to force as the last generated token when `max_length` is reached. Usually set to + `eos_token_id`. + + Example: + + ```python + >>> from transformers import PLBartConfig, PLBartModel + + >>> # Initializing a PLBART uclanlp/plbart-base style configuration + >>> configuration = PLBartConfig() + + >>> # Initializing a model (with random weights) from the uclanlp/plbart-base style configuration + >>> model = PLBartModel(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "plbart" + keys_to_ignore_at_inference = ["past_key_values"] + attribute_map = { + "num_attention_heads": "encoder_attention_heads", + "hidden_size": "d_model", + "initializer_range": "init_std", + } + + def __init__( + self, + vocab_size=50005, + max_position_embeddings=1024, + encoder_layers=6, + encoder_ffn_dim=3072, + encoder_attention_heads=12, + decoder_layers=6, + decoder_ffn_dim=3072, + decoder_attention_heads=12, + encoder_layerdrop=0.0, + decoder_layerdrop=0.0, + use_cache=True, + is_encoder_decoder=True, + activation_function="gelu", + d_model=768, + dropout=0.1, + attention_dropout=0.1, + activation_dropout=0.0, + init_std=0.02, + classifier_dropout=0.0, + scale_embedding=True, + pad_token_id=1, + bos_token_id=0, + eos_token_id=2, + forced_eos_token_id=2, + is_decoder=False, + tie_word_embeddings=True, + **kwargs, + ): + self.is_decoder = is_decoder + self.tie_word_embeddings = tie_word_embeddings + self.vocab_size = vocab_size + self.max_position_embeddings = max_position_embeddings + self.d_model = d_model + self.encoder_ffn_dim = encoder_ffn_dim + self.encoder_layers = encoder_layers + self.encoder_attention_heads = encoder_attention_heads + self.decoder_ffn_dim = decoder_ffn_dim + self.decoder_layers = decoder_layers + self.decoder_attention_heads = decoder_attention_heads + self.dropout = dropout + self.attention_dropout = attention_dropout + self.activation_dropout = activation_dropout + self.activation_function = activation_function + self.init_std = init_std + self.encoder_layerdrop = encoder_layerdrop + self.decoder_layerdrop = decoder_layerdrop + self.classifier_dropout = classifier_dropout + self.use_cache = use_cache + self.num_hidden_layers = encoder_layers + self.scale_embedding = scale_embedding # scale factor will be sqrt(d_model) if True + self.pad_token_id = pad_token_id + self.bos_token_id = bos_token_id + self.eos_token_id = eos_token_id + self.forced_eos_token_id = forced_eos_token_id + super().__init__( + is_encoder_decoder=is_encoder_decoder, + **kwargs, + ) + + +__all__ = ["PLBartConfig"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/plbart/modeling_plbart.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/plbart/modeling_plbart.py new file mode 100644 index 0000000000000000000000000000000000000000..7b3a1a42f16568d63554032f6fe19752e2be8591 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/plbart/modeling_plbart.py @@ -0,0 +1,1405 @@ +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# This file was automatically generated from src/transformers/models/plbart/modular_plbart.py. +# Do NOT edit this file manually as any edits will be overwritten by the generation of +# the file from the modular. If any change should be done, please apply the change to the +# modular_plbart.py file directly. One of our CI enforces this. +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# Copyright 2022, UCLA NLP, The Facebook AI Research Team and The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import math +from collections.abc import Callable + +import torch +from torch import nn +from torch.nn import BCEWithLogitsLoss, CrossEntropyLoss, MSELoss + +from ... import initialization as init +from ...activations import ACT2FN +from ...cache_utils import Cache, DynamicCache, EncoderDecoderCache +from ...generation import GenerationMixin +from ...masking_utils import create_bidirectional_mask, create_causal_mask +from ...modeling_flash_attention_utils import FlashAttentionKwargs +from ...modeling_layers import GradientCheckpointingLayer +from ...modeling_outputs import ( + BaseModelOutput, + BaseModelOutputWithPastAndCrossAttentions, + CausalLMOutputWithCrossAttentions, + Seq2SeqLMOutput, + Seq2SeqModelOutput, + Seq2SeqSequenceClassifierOutput, +) +from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel +from ...processing_utils import Unpack +from ...utils import TransformersKwargs, auto_docstring, is_torchdynamo_compiling, logging, torch_compilable_check +from .configuration_plbart import PLBartConfig + + +logger = logging.get_logger(__name__) + + +class PLBartScaledWordEmbedding(nn.Embedding): + """ + This module overrides nn.Embeddings' forward by multiplying with embeddings scale. + """ + + def __init__(self, num_embeddings: int, embedding_dim: int, padding_idx: int, embed_scale: float | None = 1.0): + super().__init__(num_embeddings, embedding_dim, padding_idx) + self.embed_scale = embed_scale + + def forward(self, input_ids: torch.Tensor): + return super().forward(input_ids) * self.embed_scale + + +@auto_docstring +class PLBartPreTrainedModel(PreTrainedModel): + config: PLBartConfig + base_model_prefix = "model" + supports_gradient_checkpointing = True + _no_split_modules = ["PLBartDecoderLayer", "PLBartEncoderLayer"] + _supports_flash_attn = True + _supports_sdpa = True + _supports_flex_attn = True + + def _init_weights(self, module): + super()._init_weights(module) + if isinstance(module, PLBartForConditionalGeneration): + init.zeros_(module.final_logits_bias) + + +class PLBartLearnedPositionalEmbedding(nn.Embedding): + """ + This module learns positional embeddings up to a fixed maximum size. + """ + + def __init__(self, num_embeddings: int, embedding_dim: int): + # PLBart is set up so that if padding_idx is specified then offset the embedding ids by 2 + # and adjust num_embeddings appropriately. Other models don't have this hack + self.offset = 2 + super().__init__(num_embeddings + self.offset, embedding_dim) + + def forward( + self, input_ids: torch.Tensor, past_key_values_length: int = 0, position_ids: torch.Tensor | None = None + ): + """`input_ids' shape is expected to be [bsz x seqlen].""" + + if position_ids is None: + bsz, seq_len = input_ids.shape[:2] + position_ids = torch.arange( + past_key_values_length, past_key_values_length + seq_len, dtype=torch.long, device=self.weight.device + ).expand(bsz, -1) + else: + position_ids = position_ids.unsqueeze(0) + + return super().forward(position_ids + self.offset) + + +def eager_attention_forward( + module: nn.Module, + query: torch.Tensor, + key: torch.Tensor, + value: torch.Tensor, + attention_mask: torch.Tensor | None, + scaling: float | None = None, + dropout: float = 0.0, + **kwargs: Unpack[TransformersKwargs], +): + if scaling is None: + scaling = query.size(-1) ** -0.5 + + # Take the dot product between "query" and "key" to get the raw attention scores. + attn_weights = torch.matmul(query, key.transpose(2, 3)) * scaling + + if attention_mask is not None: + attn_weights = attn_weights + attention_mask + + attn_weights = nn.functional.softmax(attn_weights, dim=-1) + attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training) + + attn_output = torch.matmul(attn_weights, value) + attn_output = attn_output.transpose(1, 2).contiguous() + + return attn_output, attn_weights + + +class PLBartAttention(nn.Module): + """Multi-headed attention from 'Attention Is All You Need' paper""" + + def __init__( + self, + embed_dim: int, + num_heads: int, + dropout: float = 0.0, + is_decoder: bool = False, + bias: bool = True, + is_causal: bool = False, + config: PLBartConfig | None = None, + layer_idx: int | None = None, + ): + super().__init__() + self.embed_dim = embed_dim + self.num_heads = num_heads + self.dropout = dropout + self.head_dim = embed_dim // num_heads + self.config = config + + if (self.head_dim * num_heads) != self.embed_dim: + raise ValueError( + f"embed_dim must be divisible by num_heads (got `embed_dim`: {self.embed_dim}" + f" and `num_heads`: {num_heads})." + ) + self.scaling = self.head_dim**-0.5 + self.is_decoder = is_decoder + self.is_causal = is_causal + self.layer_idx = layer_idx + if layer_idx is None and self.is_decoder: + logger.warning_once( + f"Instantiating a decoder {self.__class__.__name__} without passing `layer_idx` is not recommended and " + "will lead to errors during the forward call, if caching is used. Please make sure to provide a `layer_idx` " + "when creating this class." + ) + + self.k_proj = nn.Linear(embed_dim, embed_dim, bias=bias) + self.v_proj = nn.Linear(embed_dim, embed_dim, bias=bias) + self.q_proj = nn.Linear(embed_dim, embed_dim, bias=bias) + self.out_proj = nn.Linear(embed_dim, embed_dim, bias=bias) + + def forward( + self, + hidden_states: torch.Tensor, + key_value_states: torch.Tensor | None = None, + past_key_values: Cache | None = None, + attention_mask: torch.Tensor | None = None, + output_attentions: bool = False, + cache_position: torch.Tensor | None = None, + # TODO: we need a refactor so that the different attention modules can get their specific kwargs + # ATM, we have mixed things encoder, decoder, and encoder-decoder attn + **kwargs: Unpack[FlashAttentionKwargs], + ) -> tuple[torch.Tensor, torch.Tensor | None, tuple[torch.Tensor] | None]: + """Input shape: Batch x Time x Channel""" + + # if key_value_states are provided this layer is used as a cross-attention layer + # for the decoder + is_cross_attention = key_value_states is not None + + # determine input shapes + bsz, tgt_len = hidden_states.shape[:-1] + src_len = key_value_states.shape[1] if is_cross_attention else tgt_len + + q_input_shape = (bsz, tgt_len, -1, self.head_dim) + kv_input_shape = (bsz, src_len, -1, self.head_dim) + + # get query proj + query_states = self.q_proj(hidden_states).view(*q_input_shape).transpose(1, 2) + + is_updated = False + if past_key_values is not None: + if isinstance(past_key_values, EncoderDecoderCache): + is_updated = past_key_values.is_updated.get(self.layer_idx) + if is_cross_attention: + # after the first generated id, we can subsequently re-use all key/value_states from cache + curr_past_key_values = past_key_values.cross_attention_cache + else: + curr_past_key_values = past_key_values.self_attention_cache + else: + curr_past_key_values = past_key_values + + current_states = key_value_states if is_cross_attention else hidden_states + if is_cross_attention and past_key_values is not None and is_updated: + # reuse k,v, cross_attentions + key_states = curr_past_key_values.layers[self.layer_idx].keys + value_states = curr_past_key_values.layers[self.layer_idx].values + else: + key_states = self.k_proj(current_states) + value_states = self.v_proj(current_states) + key_states = key_states.view(*kv_input_shape).transpose(1, 2) + value_states = value_states.view(*kv_input_shape).transpose(1, 2) + + if past_key_values is not None: + # save all key/value_states to cache to be re-used for fast auto-regressive generation + cache_position = cache_position if not is_cross_attention else None + key_states, value_states = curr_past_key_values.update( + key_states, value_states, self.layer_idx, {"cache_position": cache_position} + ) + # set flag that curr layer for cross-attn is already updated so we can re-use in subsequent calls + if is_cross_attention and isinstance(past_key_values, EncoderDecoderCache): + past_key_values.is_updated[self.layer_idx] = True + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, eager_attention_forward + ) + + attn_output, attn_weights = attention_interface( + self, + query_states, + key_states, + value_states, + attention_mask, + dropout=0.0 if not self.training else self.dropout, + scaling=self.scaling, + output_attentions=output_attentions, + **kwargs, + ) + + attn_output = attn_output.reshape(bsz, tgt_len, -1).contiguous() + attn_output = self.out_proj(attn_output) + + return attn_output, attn_weights + + +class PLBartEncoderLayer(GradientCheckpointingLayer): + def __init__(self, config: PLBartConfig, layer_idx: int | None = None): + super().__init__() + self.embed_dim = config.d_model + + self.self_attn = PLBartAttention( + embed_dim=self.embed_dim, + num_heads=config.encoder_attention_heads, + dropout=config.attention_dropout, + config=config, + layer_idx=layer_idx, + ) + self.self_attn_layer_norm = nn.LayerNorm(self.embed_dim) + self.dropout = config.dropout + self.activation_fn = ACT2FN[config.activation_function] + self.activation_dropout = config.activation_dropout + self.fc1 = nn.Linear(self.embed_dim, config.encoder_ffn_dim) + self.fc2 = nn.Linear(config.encoder_ffn_dim, self.embed_dim) + self.final_layer_norm = nn.LayerNorm(self.embed_dim) + + def forward( + self, + hidden_states: torch.FloatTensor, + attention_mask: torch.FloatTensor, + output_attentions: bool | None = False, + ) -> tuple[torch.FloatTensor, torch.FloatTensor | None]: + """ + Args: + hidden_states (`torch.FloatTensor`): input to the layer of shape `(batch, seq_len, embed_dim)` + attention_mask (`torch.FloatTensor`): attention mask of size + `(batch, 1, tgt_len, src_len)` where padding elements are indicated by very large negative values. + output_attentions (`bool`, *optional*): + Whether or not to return the attentions tensors of all attention layers. See `attentions` under + returned tensors for more detail. + """ + residual = hidden_states + hidden_states, attn_weights = self.self_attn( + hidden_states=hidden_states, + attention_mask=attention_mask, + output_attentions=output_attentions, + ) + hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training) + hidden_states = residual + hidden_states + hidden_states = self.self_attn_layer_norm(hidden_states) + + residual = hidden_states + hidden_states = self.activation_fn(self.fc1(hidden_states)) + hidden_states = nn.functional.dropout(hidden_states, p=self.activation_dropout, training=self.training) + hidden_states = self.fc2(hidden_states) + hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training) + hidden_states = residual + hidden_states + hidden_states = self.final_layer_norm(hidden_states) + + if hidden_states.dtype == torch.float16 and not torch.isfinite(hidden_states).all(): + clamp_value = torch.finfo(hidden_states.dtype).max - 1000 + hidden_states = torch.clamp(hidden_states, min=-clamp_value, max=clamp_value) + + outputs = (hidden_states,) + + if output_attentions: + outputs += (attn_weights,) + + return outputs + + +class PLBartEncoder(PLBartPreTrainedModel): + """ + Transformer encoder consisting of *config.encoder_layers* self attention layers. Each layer is a + [`PLBartEncoderLayer`]. + + Args: + config: PLBartConfig + embed_tokens (nn.Embedding): output embedding + """ + + def __init__(self, config: PLBartConfig): + super().__init__(config) + + self.dropout = config.dropout + self.layerdrop = config.encoder_layerdrop + + embed_dim = config.d_model + self.padding_idx = config.pad_token_id + self.max_source_positions = config.max_position_embeddings + embed_scale = math.sqrt(embed_dim) if config.scale_embedding else 1.0 + + self.embed_tokens = PLBartScaledWordEmbedding( + config.vocab_size, embed_dim, self.padding_idx, embed_scale=embed_scale + ) + + self.embed_positions = PLBartLearnedPositionalEmbedding( + config.max_position_embeddings, + embed_dim, + ) + self.layers = nn.ModuleList([PLBartEncoderLayer(config, layer_idx=i) for i in range(config.encoder_layers)]) + self.layernorm_embedding = nn.LayerNorm(embed_dim) + + self.gradient_checkpointing = False + # Initialize weights and apply final processing + self.post_init() + + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.Tensor | None = None, + inputs_embeds: torch.FloatTensor | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + **kwargs, + ) -> tuple | BaseModelOutput: + r""" + Args: + input_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`): + Indices of input sequence tokens in the vocabulary. Padding will be ignored by default should you + provide it. + + Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and + [`PreTrainedTokenizer.__call__`] for details. + + [What are input IDs?](../glossary#input-ids) + attention_mask (`torch.Tensor` of shape `(batch_size, sequence_length)`, *optional*): + Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`: + + - 1 for tokens that are **not masked**, + - 0 for tokens that are **masked**. + + [What are attention masks?](../glossary#attention-mask) + inputs_embeds (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*): + Optionally, instead of passing `input_ids` you can choose to directly pass an embedded representation. + This is useful if you want more control over how to convert `input_ids` indices into associated vectors + than the model's internal embedding lookup matrix. + output_attentions (`bool`, *optional*): + Whether or not to return the attentions tensors of all attention layers. See `attentions` under + returned tensors for more detail. + output_hidden_states (`bool`, *optional*): + Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors + for more detail. + return_dict (`bool`, *optional*): + Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple. + """ + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + # retrieve input_ids and inputs_embeds + if input_ids is not None and inputs_embeds is not None: + raise ValueError("You cannot specify both input_ids and inputs_embeds at the same time") + elif input_ids is not None: + input = input_ids + input_ids = input_ids.view(-1, input_ids.shape[-1]) + elif inputs_embeds is not None: + input = inputs_embeds[:, :, -1] + else: + raise ValueError("You have to specify either input_ids or inputs_embeds") + + if inputs_embeds is None: + inputs_embeds = self.embed_tokens(input_ids) + + embed_pos = self.embed_positions(input) + embed_pos = embed_pos.to(inputs_embeds.device) + + hidden_states = inputs_embeds + embed_pos + hidden_states = self.layernorm_embedding(hidden_states) + hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training) + + attention_mask = create_bidirectional_mask( + config=self.config, + inputs_embeds=inputs_embeds, + attention_mask=attention_mask, + ) + + encoder_states = () if output_hidden_states else None + all_attentions = () if output_attentions else None + + for idx, encoder_layer in enumerate(self.layers): + if output_hidden_states: + encoder_states = encoder_states + (hidden_states,) + # add LayerDrop (see https://huggingface.co/papers/1909.11556 for description) + to_drop = False + if self.training: + dropout_probability = torch.rand([]) + if dropout_probability < self.layerdrop: # skip the layer + to_drop = True + + if to_drop: + layer_outputs = (None, None) + else: + layer_outputs = encoder_layer( + hidden_states, + attention_mask, + output_attentions=output_attentions, + ) + + hidden_states = layer_outputs[0] + + if output_attentions: + all_attentions = all_attentions + (layer_outputs[1],) + + if output_hidden_states: + encoder_states = encoder_states + (hidden_states,) + + if not return_dict: + return tuple(v for v in [hidden_states, encoder_states, all_attentions] if v is not None) + return BaseModelOutput( + last_hidden_state=hidden_states, hidden_states=encoder_states, attentions=all_attentions + ) + + +class PLBartDecoderLayer(GradientCheckpointingLayer): + def __init__(self, config: PLBartConfig, layer_idx: int | None = None): + super().__init__() + self.embed_dim = config.d_model + + self.self_attn = PLBartAttention( + embed_dim=self.embed_dim, + num_heads=config.decoder_attention_heads, + dropout=config.attention_dropout, + is_decoder=True, + is_causal=True, + config=config, + layer_idx=layer_idx, + ) + self.dropout = config.dropout + self.activation_fn = ACT2FN[config.activation_function] + self.activation_dropout = config.activation_dropout + + self.self_attn_layer_norm = nn.LayerNorm(self.embed_dim) + self.encoder_attn = PLBartAttention( + self.embed_dim, + config.decoder_attention_heads, + dropout=config.attention_dropout, + is_decoder=True, + config=config, + layer_idx=layer_idx, + ) + self.encoder_attn_layer_norm = nn.LayerNorm(self.embed_dim) + self.fc1 = nn.Linear(self.embed_dim, config.decoder_ffn_dim) + self.fc2 = nn.Linear(config.decoder_ffn_dim, self.embed_dim) + self.final_layer_norm = nn.LayerNorm(self.embed_dim) + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.Tensor | None = None, + encoder_hidden_states: torch.Tensor | None = None, + encoder_attention_mask: torch.Tensor | None = None, + past_key_values: Cache | None = None, + output_attentions: bool | None = False, + use_cache: bool | None = True, + cache_position: torch.Tensor | None = None, + ) -> tuple[torch.FloatTensor, tuple[torch.FloatTensor, torch.FloatTensor] | None]: + """ + Args: + hidden_states (`torch.FloatTensor`): input to the layer of shape `(batch, seq_len, embed_dim)` + attention_mask (`torch.FloatTensor`): attention mask of size + `(batch, 1, tgt_len, src_len)` where padding elements are indicated by very large negative values. + encoder_hidden_states (`torch.FloatTensor`): + cross attention input to the layer of shape `(batch, seq_len, embed_dim)` + encoder_attention_mask (`torch.FloatTensor`): encoder attention mask of size + `(batch, 1, tgt_len, src_len)` where padding elements are indicated by very large negative values. + past_key_values (`Cache`): cached past key and value projection states + output_attentions (`bool`, *optional*): + Whether or not to return the attentions tensors of all attention layers. See `attentions` under + returned tensors for more detail. + cache_position (`torch.LongTensor` of shape `(sequence_length)`, *optional*): + Indices depicting the position of the input sequence tokens in the sequence. It is used to update the + cache in the correct position and to infer the complete sequence length. + """ + residual = hidden_states + + # Self Attention + hidden_states, self_attn_weights = self.self_attn( + hidden_states=hidden_states, + past_key_values=past_key_values, + attention_mask=attention_mask, + output_attentions=output_attentions, + cache_position=cache_position, + ) + hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training) + hidden_states = residual + hidden_states + hidden_states = self.self_attn_layer_norm(hidden_states) + + # Cross-Attention Block + cross_attn_weights = None + if encoder_hidden_states is not None: + residual = hidden_states + + hidden_states, cross_attn_weights = self.encoder_attn( + hidden_states=hidden_states, + key_value_states=encoder_hidden_states, + attention_mask=encoder_attention_mask, + past_key_values=past_key_values, + output_attentions=output_attentions, + cache_position=cache_position, + ) + hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training) + hidden_states = residual + hidden_states + hidden_states = self.encoder_attn_layer_norm(hidden_states) + + # Fully Connected + residual = hidden_states + hidden_states = self.activation_fn(self.fc1(hidden_states)) + hidden_states = nn.functional.dropout(hidden_states, p=self.activation_dropout, training=self.training) + hidden_states = self.fc2(hidden_states) + hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training) + hidden_states = residual + hidden_states + hidden_states = self.final_layer_norm(hidden_states) + + outputs = (hidden_states,) + + if output_attentions: + outputs += (self_attn_weights, cross_attn_weights) + + return outputs + + +class PLBartDecoder(PLBartPreTrainedModel): + """ + Transformer decoder consisting of *config.decoder_layers* layers. Each layer is a [`PLBartDecoderLayer`] + + Args: + config: PLBartConfig + embed_tokens (nn.Embedding): output embedding + """ + + def __init__(self, config: PLBartConfig): + super().__init__(config) + self.dropout = config.dropout + self.layerdrop = config.decoder_layerdrop + self.padding_idx = config.pad_token_id + self.max_target_positions = config.max_position_embeddings + embed_scale = math.sqrt(config.d_model) if config.scale_embedding else 1.0 + + self.embed_tokens = PLBartScaledWordEmbedding( + config.vocab_size, config.d_model, self.padding_idx, embed_scale=embed_scale + ) + + self.embed_positions = PLBartLearnedPositionalEmbedding( + config.max_position_embeddings, + config.d_model, + ) + self.layers = nn.ModuleList([PLBartDecoderLayer(config, layer_idx=i) for i in range(config.decoder_layers)]) + + self.layernorm_embedding = nn.LayerNorm(config.d_model) + + self.gradient_checkpointing = False + # Initialize weights and apply final processing + self.post_init() + + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.Tensor | None = None, + encoder_hidden_states: torch.FloatTensor | None = None, + encoder_attention_mask: torch.LongTensor | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.FloatTensor | None = None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + cache_position: torch.LongTensor | None = None, + **kwargs, + ) -> tuple | BaseModelOutputWithPastAndCrossAttentions: + r""" + Args: + input_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`): + Indices of input sequence tokens in the vocabulary. Padding will be ignored by default should you + provide it. + + Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and + [`PreTrainedTokenizer.__call__`] for details. + + [What are input IDs?](../glossary#input-ids) + attention_mask (`torch.Tensor` of shape `(batch_size, sequence_length)`, *optional*): + Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`: + + - 1 for tokens that are **not masked**, + - 0 for tokens that are **masked**. + + [What are attention masks?](../glossary#attention-mask) + encoder_hidden_states (`torch.FloatTensor` of shape `(batch_size, encoder_sequence_length, hidden_size)`, *optional*): + Sequence of hidden-states at the output of the last layer of the encoder. Used in the cross-attention + of the decoder. + encoder_attention_mask (`torch.LongTensor` of shape `(batch_size, encoder_sequence_length)`, *optional*): + Mask to avoid performing cross-attention on padding tokens indices of encoder input_ids. Mask values + selected in `[0, 1]`: + + - 1 for tokens that are **not masked**, + - 0 for tokens that are **masked**. + + [What are attention masks?](../glossary#attention-mask) + past_key_values (`Cache`, *optional*, returned when `use_cache=True` is passed or when `config.use_cache=True`): + It is a [`~cache_utils.Cache`] instance. For more details, see our [kv cache guide](https://huggingface.co/docs/transformers/en/kv_cache). + + Contains pre-computed hidden-states (key and values in the self-attention blocks and in the + cross-attention blocks) that can be used (see `past_key_values` input) to speed up sequential decoding. + + If `past_key_values` are used, the user can optionally input only the last `decoder_input_ids` (those + that don't have their past key value states given to this model) of shape `(batch_size, 1)` instead of + all `decoder_input_ids` of shape `(batch_size, sequence_length)`. + inputs_embeds (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*): + Optionally, instead of passing `input_ids` you can choose to directly pass an embedded representation. + This is useful if you want more control over how to convert `input_ids` indices into associated vectors + than the model's internal embedding lookup matrix. + output_attentions (`bool`, *optional*): + Whether or not to return the attentions tensors of all attention layers. See `attentions` under + returned tensors for more detail. + output_hidden_states (`bool`, *optional*): + Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors + for more detail. + return_dict (`bool`, *optional*): + Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple. + cache_position (`torch.LongTensor` of shape `(sequence_length)`, *optional*): + Indices depicting the position of the input sequence tokens in the sequence. It is used to update the + cache in the correct position and to infer the complete sequence length. + """ + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + use_cache = use_cache if use_cache is not None else self.config.use_cache + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + if self.gradient_checkpointing and self.training: + if use_cache: + logger.warning_once( + "`use_cache=True` is incompatible with gradient checkpointing. Setting `use_cache=False`..." + ) + use_cache = False + + # retrieve input_ids and inputs_embeds + if (input_ids is None) ^ (inputs_embeds is not None): + raise ValueError("You cannot specify both decoder_input_ids and decoder_inputs_embeds at the same time") + elif input_ids is not None: + input = input_ids + input_shape = input.shape + input_ids = input_ids.view(-1, input_shape[-1]) + elif inputs_embeds is not None: + input_shape = inputs_embeds.size()[:-1] + input = inputs_embeds[:, :, -1] + else: + raise ValueError("You have to specify either decoder_input_ids or decoder_inputs_embeds") + + if inputs_embeds is None: + inputs_embeds = self.embed_tokens(input) + + # initialize `past_key_values` + if use_cache and past_key_values is None: + past_key_values = ( + EncoderDecoderCache(DynamicCache(config=self.config), DynamicCache(config=self.config)) + if encoder_hidden_states is not None or self.config.is_encoder_decoder + else DynamicCache(config=self.config) + ) + + batch_size, seq_length = inputs_embeds.size()[:-1] + past_key_values_length = past_key_values.get_seq_length() if past_key_values is not None else 0 + if cache_position is None: + cache_position = torch.arange( + past_key_values_length, past_key_values_length + seq_length, device=inputs_embeds.device + ) + + if attention_mask is None and not is_torchdynamo_compiling(): + # required mask seq length can be calculated via length of past cache + mask_seq_length = past_key_values_length + seq_length + attention_mask = torch.ones(batch_size, mask_seq_length, device=inputs_embeds.device) + + self_attn_cache = ( + past_key_values.self_attention_cache + if isinstance(past_key_values, EncoderDecoderCache) + else past_key_values + ) + + attention_mask = create_causal_mask( + config=self.config, + inputs_embeds=inputs_embeds, + attention_mask=attention_mask, + cache_position=cache_position, + past_key_values=self_attn_cache, + ) + encoder_attention_mask = create_bidirectional_mask( + config=self.config, + inputs_embeds=inputs_embeds, + attention_mask=encoder_attention_mask, + encoder_hidden_states=encoder_hidden_states, + ) + + # embed positions + positions = self.embed_positions(input, past_key_values_length, position_ids=cache_position) + positions = positions.to(inputs_embeds.device) + + hidden_states = inputs_embeds + positions + hidden_states = self.layernorm_embedding(hidden_states) + + hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training) + + # decoder layers + all_hidden_states = () if output_hidden_states else None + all_self_attns = () if output_attentions else None + all_cross_attentions = () if (output_attentions and encoder_hidden_states is not None) else None + + for idx, decoder_layer in enumerate(self.layers): + # add LayerDrop (see https://huggingface.co/papers/1909.11556 for description) + if output_hidden_states: + all_hidden_states += (hidden_states,) + if self.training: + dropout_probability = torch.rand([]) + if dropout_probability < self.layerdrop: + continue + + layer_outputs = decoder_layer( + hidden_states, + attention_mask, + encoder_hidden_states, # as a positional argument for gradient checkpointing + encoder_attention_mask=encoder_attention_mask, + past_key_values=past_key_values, + output_attentions=output_attentions, + use_cache=use_cache, + cache_position=cache_position, + ) + hidden_states = layer_outputs[0] + if output_attentions: + all_self_attns += (layer_outputs[1],) + + if encoder_hidden_states is not None: + all_cross_attentions += (layer_outputs[2],) + + # add hidden states from the last decoder layer + if output_hidden_states: + all_hidden_states += (hidden_states,) + + if not return_dict: + return tuple( + v + for v in [hidden_states, past_key_values, all_hidden_states, all_self_attns, all_cross_attentions] + if v is not None + ) + return BaseModelOutputWithPastAndCrossAttentions( + last_hidden_state=hidden_states, + past_key_values=past_key_values, + hidden_states=all_hidden_states, + attentions=all_self_attns, + cross_attentions=all_cross_attentions, + ) + + +def shift_tokens_right(input_ids: torch.Tensor, pad_token_id: int): + """ + Shift input ids one token to the right, and wrap the last non pad token (the token) Note that PLBart does not + have a single `decoder_start_token_id` in contrast to other Bart-like models. + """ + prev_output_tokens = input_ids.clone() + + if pad_token_id is None: + raise ValueError("self.model.config.pad_token_id has to be defined.") + # replace possible -100 values in labels by `pad_token_id` + prev_output_tokens.masked_fill_(prev_output_tokens == -100, pad_token_id) + + index_of_eos = (prev_output_tokens.ne(pad_token_id).sum(dim=1) - 1).unsqueeze(-1) + decoder_start_tokens = prev_output_tokens.gather(1, index_of_eos).squeeze() + prev_output_tokens[:, 1:] = prev_output_tokens[:, :-1].clone() + prev_output_tokens[:, 0] = decoder_start_tokens + + return prev_output_tokens + + +@auto_docstring +class PLBartModel(PLBartPreTrainedModel): + _tied_weights_keys = { + "encoder.embed_tokens.weight": "shared.weight", + "decoder.embed_tokens.weight": "shared.weight", + } + + def __init__(self, config: PLBartConfig): + super().__init__(config) + + padding_idx, vocab_size = config.pad_token_id, config.vocab_size + embed_scale = math.sqrt(config.d_model) if config.scale_embedding else 1.0 + self.shared = PLBartScaledWordEmbedding(vocab_size, config.d_model, padding_idx, embed_scale=embed_scale) + + self.encoder = PLBartEncoder(config) + self.decoder = PLBartDecoder(config) + + self.post_init() + + def get_input_embeddings(self): + return self.shared + + def set_input_embeddings(self, value): + self.shared = value + self.encoder.embed_tokens = self.shared + self.decoder.embed_tokens = self.shared + + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.LongTensor | None = None, + decoder_input_ids: torch.LongTensor | None = None, + decoder_attention_mask: torch.Tensor | None = None, + encoder_outputs: list[torch.FloatTensor] | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.FloatTensor | None = None, + decoder_inputs_embeds: torch.FloatTensor | None = None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + cache_position: torch.LongTensor | None = None, + **kwargs, + ) -> tuple[torch.Tensor] | Seq2SeqModelOutput: + r""" + decoder_input_ids (`torch.LongTensor` of shape `(batch_size, target_sequence_length)`, *optional*): + Indices of decoder input sequence tokens in the vocabulary. + + Indices can be obtained using [`AutoTokenizer`] or [`PLBartMultiTokenizer`] depending on the checkpoint. + See [`PreTrainedTokenizer.encode`] and [`PreTrainedTokenizer.__call__`] for details. + + [What are decoder input IDs?](../glossary#decoder-input-ids) + + PLBart uses a specific language id token as the starting token for `decoder_input_ids` generation that + varies according to source and target language, *e.g.* 50003 for *en_XX*, and 50001 for *java*. If + `past_key_values` is used, optionally only the last `decoder_input_ids` have to be input (see + `past_key_values`). + + For translation and summarization training, `decoder_input_ids` should be provided. If no + `decoder_input_ids` is provided, the model will create this tensor by shifting the `input_ids` to the right + for denoising pre-training following the paper. + decoder_attention_mask (: + obj:*torch.LongTensor* of shape `(batch_size, target_sequence_length)`, *optional*): + Default behavior: + generate a tensor that ignores pad tokens in `decoder_input_ids`. Causal mask will also be used by default. + """ + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + use_cache = use_cache if use_cache is not None else self.config.use_cache + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + # different to other models, PLBart automatically creates decoder_input_ids from + # input_ids if no decoder_input_ids are provided + if decoder_input_ids is None and decoder_inputs_embeds is None: + decoder_input_ids = shift_tokens_right(input_ids, self.config.pad_token_id) + + if encoder_outputs is None: + encoder_outputs = self.encoder( + input_ids=input_ids, + attention_mask=attention_mask, + inputs_embeds=inputs_embeds, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + # If the user passed a tuple for encoder_outputs, we wrap it in a BaseModelOutput when return_dict=True + elif return_dict and not isinstance(encoder_outputs, BaseModelOutput): + encoder_outputs = BaseModelOutput( + last_hidden_state=encoder_outputs[0], + hidden_states=encoder_outputs[1] if len(encoder_outputs) > 1 else None, + attentions=encoder_outputs[2] if len(encoder_outputs) > 2 else None, + ) + + # decoder outputs consists of (dec_features, past_key_values, dec_hidden, dec_attn) + decoder_outputs = self.decoder( + input_ids=decoder_input_ids, + attention_mask=decoder_attention_mask, + encoder_hidden_states=encoder_outputs[0], + encoder_attention_mask=attention_mask, + past_key_values=past_key_values, + inputs_embeds=decoder_inputs_embeds, + use_cache=use_cache, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + cache_position=cache_position, + ) + + if not return_dict: + return decoder_outputs + encoder_outputs + + return Seq2SeqModelOutput( + last_hidden_state=decoder_outputs.last_hidden_state, + past_key_values=decoder_outputs.past_key_values, + decoder_hidden_states=decoder_outputs.hidden_states, + decoder_attentions=decoder_outputs.attentions, + cross_attentions=decoder_outputs.cross_attentions, + encoder_last_hidden_state=encoder_outputs.last_hidden_state, + encoder_hidden_states=encoder_outputs.hidden_states, + encoder_attentions=encoder_outputs.attentions, + ) + + +@auto_docstring( + custom_intro=""" + The PLBART Model with a language modeling head. Can be used for code-to-text, text-to-code and code-to-code. + """ +) +class PLBartForConditionalGeneration(PLBartPreTrainedModel, GenerationMixin): + base_model_prefix = "model" + _keys_to_ignore_on_load_missing = ["final_logits_bias"] + _tied_weights_keys = { + "lm_head.weight": "model.shared.weight", + } + + def __init__(self, config: PLBartConfig): + super().__init__(config) + self.model = PLBartModel(config) + self.register_buffer("final_logits_bias", torch.zeros((1, self.model.shared.num_embeddings))) + self.lm_head = nn.Linear(config.d_model, self.model.shared.num_embeddings, bias=False) + + self.post_init() + + def resize_token_embeddings( + self, new_num_tokens: int, pad_to_multiple_of: int | None = None, mean_resizing: bool = True + ) -> nn.Embedding: + new_embeddings = super().resize_token_embeddings(new_num_tokens, pad_to_multiple_of, mean_resizing) + self._resize_final_logits_bias(new_embeddings.weight.shape[0]) + return new_embeddings + + def _resize_final_logits_bias(self, new_num_tokens: int) -> None: + old_num_tokens = self.final_logits_bias.shape[-1] + if new_num_tokens <= old_num_tokens: + new_bias = self.final_logits_bias[:, :new_num_tokens] + else: + extra_bias = torch.zeros((1, new_num_tokens - old_num_tokens), device=self.final_logits_bias.device) + new_bias = torch.cat([self.final_logits_bias, extra_bias], dim=1) + self.register_buffer("final_logits_bias", new_bias) + + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.LongTensor | None = None, + decoder_input_ids: torch.LongTensor | None = None, + decoder_attention_mask: torch.Tensor | None = None, + encoder_outputs: list[torch.FloatTensor] | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.FloatTensor | None = None, + decoder_inputs_embeds: torch.FloatTensor | None = None, + labels: torch.Tensor | None = None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + cache_position: torch.LongTensor | None = None, + **kwargs, + ) -> tuple[torch.Tensor] | Seq2SeqLMOutput: + r""" + decoder_input_ids (`torch.LongTensor` of shape `(batch_size, target_sequence_length)`, *optional*): + Indices of decoder input sequence tokens in the vocabulary. + + Indices can be obtained using [`AutoTokenizer`] or [`PLBartMultiTokenizer`] depending on the checkpoint. + See [`PreTrainedTokenizer.encode`] and [`PreTrainedTokenizer.__call__`] for details. + + [What are decoder input IDs?](../glossary#decoder-input-ids) + + PLBart uses a specific language id token as the starting token for `decoder_input_ids` generation that + varies according to source and target language, *e.g.* 50003 for *en_XX*, and 50001 for *java*. If + `past_key_values` is used, optionally only the last `decoder_input_ids` have to be input (see + `past_key_values`). + + For translation and summarization training, `decoder_input_ids` should be provided. If no + `decoder_input_ids` is provided, the model will create this tensor by shifting the `input_ids` to the right + for denoising pre-training following the paper. + decoder_attention_mask (: + obj:*torch.LongTensor* of shape `(batch_size, target_sequence_length)`, *optional*): + Default behavior: + generate a tensor that ignores pad tokens in `decoder_input_ids`. Causal mask will also be used by default. + labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Labels for computing the masked language modeling loss. Indices should either be in `[0, ..., + config.vocab_size]` or -100 (see `input_ids` docstring). Tokens with indices set to `-100` are ignored + (masked), the loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]`. + + Example Mask-filling: + + ```python + >>> from transformers import AutoTokenizer, PLBartForConditionalGeneration + + >>> model = PLBartForConditionalGeneration.from_pretrained("uclanlp/plbart-base") + >>> tokenizer = AutoTokenizer.from_pretrained("uclanlp/plbart-base") + + >>> # en_XX is the language symbol id for English + >>> TXT = " Is 0 the Fibonacci number ? en_XX" + >>> input_ids = tokenizer([TXT], add_special_tokens=False, return_tensors="pt").input_ids + + >>> logits = model(input_ids).logits + >>> masked_index = (input_ids[0] == tokenizer.mask_token_id).nonzero().item() + >>> probs = logits[0, masked_index].softmax(dim=0) + >>> values, predictions = probs.topk(5) + + >>> tokenizer.decode(predictions).split() + ['first', 'same', 'highest', 'result', 'number'] + ``` + """ + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + if labels is not None: + if decoder_input_ids is None and decoder_inputs_embeds is None: + decoder_input_ids = shift_tokens_right(labels, self.config.pad_token_id) + + outputs = self.model( + input_ids, + attention_mask=attention_mask, + decoder_input_ids=decoder_input_ids, + encoder_outputs=encoder_outputs, + decoder_attention_mask=decoder_attention_mask, + past_key_values=past_key_values, + inputs_embeds=inputs_embeds, + decoder_inputs_embeds=decoder_inputs_embeds, + use_cache=use_cache, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + cache_position=cache_position, + ) + lm_logits = self.lm_head(outputs[0]) + lm_logits = lm_logits + self.final_logits_bias.to(lm_logits.device) + + masked_lm_loss = None + if labels is not None: + loss_fct = CrossEntropyLoss() + masked_lm_loss = loss_fct(lm_logits.view(-1, self.config.vocab_size), labels.view(-1)) + + if not return_dict: + output = (lm_logits,) + outputs[1:] + return ((masked_lm_loss,) + output) if masked_lm_loss is not None else output + + return Seq2SeqLMOutput( + loss=masked_lm_loss, + logits=lm_logits, + past_key_values=outputs.past_key_values, + decoder_hidden_states=outputs.decoder_hidden_states, + decoder_attentions=outputs.decoder_attentions, + cross_attentions=outputs.cross_attentions, + encoder_last_hidden_state=outputs.encoder_last_hidden_state, + encoder_hidden_states=outputs.encoder_hidden_states, + encoder_attentions=outputs.encoder_attentions, + ) + + def prepare_decoder_input_ids_from_labels(self, labels: torch.Tensor): + return shift_tokens_right(labels, self.config.pad_token_id) + + +class PLBartClassificationHead(nn.Module): + """Head for sentence-level classification tasks.""" + + def __init__( + self, + input_dim: int, + inner_dim: int, + num_classes: int, + pooler_dropout: float, + ): + super().__init__() + self.dense = nn.Linear(input_dim, inner_dim) + self.dropout = nn.Dropout(p=pooler_dropout) + self.out_proj = nn.Linear(inner_dim, num_classes) + + def forward(self, hidden_states: torch.Tensor) -> torch.Tensor: + hidden_states = self.dropout(hidden_states) + hidden_states = self.dense(hidden_states) + hidden_states = torch.tanh(hidden_states) + hidden_states = self.dropout(hidden_states) + hidden_states = self.out_proj(hidden_states) + return hidden_states + + +@auto_docstring( + custom_intro=""" + PLBart model with a sequence classification/head on top (a linear layer on top of the pooled output) e.g. + for GLUE tasks. + """ +) +class PLBartForSequenceClassification(PLBartPreTrainedModel): + def __init__(self, config: PLBartConfig, **kwargs): + super().__init__(config, **kwargs) + self.model = PLBartModel(config) + self.classification_head = PLBartClassificationHead( + config.d_model, + config.d_model, + config.num_labels, + config.classifier_dropout, + ) + + # Initialize weights and apply final processing + self.post_init() + + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.Tensor | None = None, + decoder_input_ids: torch.LongTensor | None = None, + decoder_attention_mask: torch.LongTensor | None = None, + encoder_outputs: list[torch.FloatTensor] | None = None, + inputs_embeds: torch.FloatTensor | None = None, + decoder_inputs_embeds: torch.FloatTensor | None = None, + labels: torch.LongTensor | None = None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + cache_position: torch.LongTensor | None = None, + **kwargs, + ) -> tuple | Seq2SeqSequenceClassifierOutput: + r""" + decoder_input_ids (`torch.LongTensor` of shape `(batch_size, target_sequence_length)`, *optional*): + Indices of decoder input sequence tokens in the vocabulary. + + Indices can be obtained using [`AutoTokenizer`] or [`PLBartMultiTokenizer`] depending on the checkpoint. + See [`PreTrainedTokenizer.encode`] and [`PreTrainedTokenizer.__call__`] for details. + + [What are decoder input IDs?](../glossary#decoder-input-ids) + + PLBart uses a specific language id token as the starting token for `decoder_input_ids` generation that + varies according to source and target language, *e.g.* 50003 for *en_XX*, and 50001 for *java*. If + `past_key_values` is used, optionally only the last `decoder_input_ids` have to be input (see + `past_key_values`). + + For translation and summarization training, `decoder_input_ids` should be provided. If no + `decoder_input_ids` is provided, the model will create this tensor by shifting the `input_ids` to the right + for denoising pre-training following the paper. + decoder_attention_mask (: + obj:*torch.LongTensor* of shape `(batch_size, target_sequence_length)`, *optional*): + Default behavior: + generate a tensor that ignores pad tokens in `decoder_input_ids`. Causal mask will also be used by default. + labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*): + Labels for computing the sequence classification/regression loss. Indices should be in `[0, ..., + config.num_labels - 1]`. If `config.num_labels > 1` a classification loss is computed (Cross-Entropy). + """ + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + if labels is not None: + use_cache = False + + if input_ids is None and inputs_embeds is not None: + raise NotImplementedError( + f"Passing input embeddings is currently not supported for {self.__class__.__name__}" + ) + + outputs = self.model( + input_ids, + attention_mask=attention_mask, + decoder_input_ids=decoder_input_ids, + decoder_attention_mask=decoder_attention_mask, + encoder_outputs=encoder_outputs, + inputs_embeds=inputs_embeds, + decoder_inputs_embeds=decoder_inputs_embeds, + use_cache=use_cache, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + cache_position=cache_position, + ) + hidden_states = outputs[0] # last hidden state + + eos_mask = input_ids.eq(self.config.eos_token_id).to(hidden_states.device) + + torch_compilable_check( + torch.unique_consecutive(eos_mask.sum(1)).numel() == 1, + "All examples must have the same number of tokens.", + ) + sentence_representation = hidden_states[eos_mask, :].view(hidden_states.size(0), -1, hidden_states.size(-1))[ + :, -1, : + ] + logits = self.classification_head(sentence_representation) + + loss = None + if labels is not None: + labels = labels.to(logits.device) + if self.config.problem_type is None: + if self.config.num_labels == 1: + self.config.problem_type = "regression" + elif self.config.num_labels > 1 and (labels.dtype == torch.long or labels.dtype == torch.int): + self.config.problem_type = "single_label_classification" + else: + self.config.problem_type = "multi_label_classification" + + if self.config.problem_type == "regression": + loss_fct = MSELoss() + if self.config.num_labels == 1: + loss = loss_fct(logits.squeeze(), labels.squeeze()) + else: + loss = loss_fct(logits, labels) + elif self.config.problem_type == "single_label_classification": + loss_fct = CrossEntropyLoss() + loss = loss_fct(logits.view(-1, self.config.num_labels), labels.view(-1)) + elif self.config.problem_type == "multi_label_classification": + loss_fct = BCEWithLogitsLoss() + loss = loss_fct(logits, labels) + if not return_dict: + output = (logits,) + outputs[1:] + return ((loss,) + output) if loss is not None else output + + return Seq2SeqSequenceClassifierOutput( + loss=loss, + logits=logits, + past_key_values=outputs.past_key_values, + decoder_hidden_states=outputs.decoder_hidden_states, + decoder_attentions=outputs.decoder_attentions, + cross_attentions=outputs.cross_attentions, + encoder_last_hidden_state=outputs.encoder_last_hidden_state, + encoder_hidden_states=outputs.encoder_hidden_states, + encoder_attentions=outputs.encoder_attentions, + ) + + +class PLBartDecoderWrapper(PLBartPreTrainedModel): + """ + This wrapper class is a helper class to correctly load pretrained checkpoints when the causal language model is + used in combination with the [`EncoderDecoderModel`] framework. + """ + + def __init__(self, config): + super().__init__(config) + self.decoder = PLBartDecoder(config) + self.post_init() + + def forward(self, *args, **kwargs): + return self.decoder(*args, **kwargs) + + +@auto_docstring( + custom_intro=""" + PLBART decoder with a language modeling head on top (linear layer with weights tied to the input embeddings). + """ +) +class PLBartForCausalLM(PLBartPreTrainedModel, GenerationMixin): + _tied_weights_keys = { + "lm_head.weight": "model.decoder.embed_tokens.weight", + } + + def __init__(self, config): + config.is_decoder = True + config.is_encoder_decoder = False + super().__init__(config) + self.model = PLBartDecoderWrapper(config) + + self.lm_head = nn.Linear(config.hidden_size, config.vocab_size, bias=False) + + # Initialize weights and apply final processing + self.post_init() + + def get_input_embeddings(self): + return self.model.decoder.embed_tokens + + def set_input_embeddings(self, value): + self.model.decoder.embed_tokens = value + + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.Tensor | None = None, + encoder_hidden_states: torch.FloatTensor | None = None, + encoder_attention_mask: torch.FloatTensor | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.FloatTensor | None = None, + labels: torch.LongTensor | None = None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + cache_position: torch.LongTensor | None = None, + logits_to_keep: int | torch.Tensor = 0, + **kwargs, + ) -> tuple | CausalLMOutputWithCrossAttentions: + r""" + labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Labels for computing the masked language modeling loss. Indices should either be in `[0, ..., + config.vocab_size]` or -100 (see `input_ids` docstring). Tokens with indices set to `-100` are ignored + (masked), the loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]`. + + Example: + + ```python + >>> from transformers import AutoTokenizer, PLBartForCausalLM + + >>> tokenizer = AutoTokenizer.from_pretrained("uclanlp/plbart-base") + >>> model = PLBartForCausalLM.from_pretrained("uclanlp/plbart-base") + >>> assert model.config.is_decoder, f"{model.__class__} has to be configured as a decoder." + >>> inputs = tokenizer("Hello, my dog is cute", return_tensors="pt") + >>> outputs = model(**inputs) + + >>> logits = outputs.logits + >>> expected_shape = [1, inputs.input_ids.shape[-1], model.config.vocab_size] + >>> list(logits.shape) == expected_shape + True + ```""" + + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + # decoder outputs consists of (dec_features, layer_state, dec_hidden, dec_attn) + outputs = self.model.decoder( + input_ids=input_ids, + attention_mask=attention_mask, + encoder_hidden_states=encoder_hidden_states, + encoder_attention_mask=encoder_attention_mask, + past_key_values=past_key_values, + inputs_embeds=inputs_embeds, + use_cache=use_cache, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + cache_position=cache_position, + ) + + hidden_states = outputs[0] + # Only compute necessary logits + slice_indices = slice(-logits_to_keep, None) if isinstance(logits_to_keep, int) else logits_to_keep + logits = self.lm_head(hidden_states[:, slice_indices, :]) + + loss = None + if labels is not None: + labels = labels.to(logits.device) + loss_fct = CrossEntropyLoss() + loss = loss_fct(logits.view(-1, self.config.vocab_size), labels.view(-1)) + + if not return_dict: + output = (logits,) + outputs[1:] + return (loss,) + output if loss is not None else output + + return CausalLMOutputWithCrossAttentions( + loss=loss, + logits=logits, + past_key_values=outputs.past_key_values, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + cross_attentions=outputs.cross_attentions, + ) + + +__all__ = [ + "PLBartForCausalLM", + "PLBartForConditionalGeneration", + "PLBartForSequenceClassification", + "PLBartModel", + "PLBartPreTrainedModel", +] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/plbart/modular_plbart.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/plbart/modular_plbart.py new file mode 100644 index 0000000000000000000000000000000000000000..1cbaa3ba707f4aa8a4e422bb883f0fb2ca46c474 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/plbart/modular_plbart.py @@ -0,0 +1,417 @@ +# Copyright 2022, UCLA NLP, The Facebook AI Research Team and The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""PyTorch PLBART model.""" + +import math + +import torch +from torch import nn +from torch.nn import CrossEntropyLoss + +from ... import initialization as init +from ...cache_utils import Cache +from ...generation import GenerationMixin +from ...modeling_outputs import ( + BaseModelOutput, + Seq2SeqLMOutput, + Seq2SeqModelOutput, +) +from ...modeling_utils import PreTrainedModel +from ...utils import auto_docstring +from ..bart.modeling_bart import ( + BartClassificationHead, + BartDecoder, + BartEncoder, + BartForCausalLM, + BartScaledWordEmbedding, +) +from ..bigbird_pegasus.modeling_bigbird_pegasus import BigBirdPegasusForSequenceClassification +from ..mbart.modeling_mbart import shift_tokens_right +from .configuration_plbart import PLBartConfig + + +class PLBartScaledWordEmbedding(BartScaledWordEmbedding): + pass + + +@auto_docstring +class PLBartPreTrainedModel(PreTrainedModel): + config: PLBartConfig + base_model_prefix = "model" + supports_gradient_checkpointing = True + _no_split_modules = ["PLBartDecoderLayer", "PLBartEncoderLayer"] + _supports_flash_attn = True + _supports_sdpa = True + _supports_flex_attn = True + + def _init_weights(self, module): + super()._init_weights(module) + if isinstance(module, PLBartForConditionalGeneration): + init.zeros_(module.final_logits_bias) + + +class PLBartEncoder(BartEncoder): + pass + + +class PLBartDecoder(BartDecoder): + pass + + +@auto_docstring +class PLBartModel(PLBartPreTrainedModel): + _tied_weights_keys = { + "encoder.embed_tokens.weight": "shared.weight", + "decoder.embed_tokens.weight": "shared.weight", + } + + def __init__(self, config: PLBartConfig): + super().__init__(config) + + padding_idx, vocab_size = config.pad_token_id, config.vocab_size + embed_scale = math.sqrt(config.d_model) if config.scale_embedding else 1.0 + self.shared = PLBartScaledWordEmbedding(vocab_size, config.d_model, padding_idx, embed_scale=embed_scale) + + self.encoder = PLBartEncoder(config) + self.decoder = PLBartDecoder(config) + + self.post_init() + + def get_input_embeddings(self): + return self.shared + + def set_input_embeddings(self, value): + self.shared = value + self.encoder.embed_tokens = self.shared + self.decoder.embed_tokens = self.shared + + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.LongTensor | None = None, + decoder_input_ids: torch.LongTensor | None = None, + decoder_attention_mask: torch.Tensor | None = None, + encoder_outputs: list[torch.FloatTensor] | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.FloatTensor | None = None, + decoder_inputs_embeds: torch.FloatTensor | None = None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + cache_position: torch.LongTensor | None = None, + **kwargs, + ) -> tuple[torch.Tensor] | Seq2SeqModelOutput: + r""" + decoder_input_ids (`torch.LongTensor` of shape `(batch_size, target_sequence_length)`, *optional*): + Indices of decoder input sequence tokens in the vocabulary. + + Indices can be obtained using [`AutoTokenizer`] or [`PLBartMultiTokenizer`] depending on the checkpoint. + See [`PreTrainedTokenizer.encode`] and [`PreTrainedTokenizer.__call__`] for details. + + [What are decoder input IDs?](../glossary#decoder-input-ids) + + PLBart uses a specific language id token as the starting token for `decoder_input_ids` generation that + varies according to source and target language, *e.g.* 50003 for *en_XX*, and 50001 for *java*. If + `past_key_values` is used, optionally only the last `decoder_input_ids` have to be input (see + `past_key_values`). + + For translation and summarization training, `decoder_input_ids` should be provided. If no + `decoder_input_ids` is provided, the model will create this tensor by shifting the `input_ids` to the right + for denoising pre-training following the paper. + decoder_attention_mask (: + obj:*torch.LongTensor* of shape `(batch_size, target_sequence_length)`, *optional*): + Default behavior: + generate a tensor that ignores pad tokens in `decoder_input_ids`. Causal mask will also be used by default. + """ + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + use_cache = use_cache if use_cache is not None else self.config.use_cache + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + # different to other models, PLBart automatically creates decoder_input_ids from + # input_ids if no decoder_input_ids are provided + if decoder_input_ids is None and decoder_inputs_embeds is None: + decoder_input_ids = shift_tokens_right(input_ids, self.config.pad_token_id) + + if encoder_outputs is None: + encoder_outputs = self.encoder( + input_ids=input_ids, + attention_mask=attention_mask, + inputs_embeds=inputs_embeds, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + # If the user passed a tuple for encoder_outputs, we wrap it in a BaseModelOutput when return_dict=True + elif return_dict and not isinstance(encoder_outputs, BaseModelOutput): + encoder_outputs = BaseModelOutput( + last_hidden_state=encoder_outputs[0], + hidden_states=encoder_outputs[1] if len(encoder_outputs) > 1 else None, + attentions=encoder_outputs[2] if len(encoder_outputs) > 2 else None, + ) + + # decoder outputs consists of (dec_features, past_key_values, dec_hidden, dec_attn) + decoder_outputs = self.decoder( + input_ids=decoder_input_ids, + attention_mask=decoder_attention_mask, + encoder_hidden_states=encoder_outputs[0], + encoder_attention_mask=attention_mask, + past_key_values=past_key_values, + inputs_embeds=decoder_inputs_embeds, + use_cache=use_cache, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + cache_position=cache_position, + ) + + if not return_dict: + return decoder_outputs + encoder_outputs + + return Seq2SeqModelOutput( + last_hidden_state=decoder_outputs.last_hidden_state, + past_key_values=decoder_outputs.past_key_values, + decoder_hidden_states=decoder_outputs.hidden_states, + decoder_attentions=decoder_outputs.attentions, + cross_attentions=decoder_outputs.cross_attentions, + encoder_last_hidden_state=encoder_outputs.last_hidden_state, + encoder_hidden_states=encoder_outputs.hidden_states, + encoder_attentions=encoder_outputs.attentions, + ) + + +@auto_docstring( + custom_intro=""" + The PLBART Model with a language modeling head. Can be used for code-to-text, text-to-code and code-to-code. + """ +) +class PLBartForConditionalGeneration(PLBartPreTrainedModel, GenerationMixin): + base_model_prefix = "model" + _keys_to_ignore_on_load_missing = ["final_logits_bias"] + _tied_weights_keys = { + "lm_head.weight": "model.shared.weight", + } + + def __init__(self, config: PLBartConfig): + super().__init__(config) + self.model = PLBartModel(config) + self.register_buffer("final_logits_bias", torch.zeros((1, self.model.shared.num_embeddings))) + self.lm_head = nn.Linear(config.d_model, self.model.shared.num_embeddings, bias=False) + + self.post_init() + + def resize_token_embeddings( + self, new_num_tokens: int, pad_to_multiple_of: int | None = None, mean_resizing: bool = True + ) -> nn.Embedding: + new_embeddings = super().resize_token_embeddings(new_num_tokens, pad_to_multiple_of, mean_resizing) + self._resize_final_logits_bias(new_embeddings.weight.shape[0]) + return new_embeddings + + def _resize_final_logits_bias(self, new_num_tokens: int) -> None: + old_num_tokens = self.final_logits_bias.shape[-1] + if new_num_tokens <= old_num_tokens: + new_bias = self.final_logits_bias[:, :new_num_tokens] + else: + extra_bias = torch.zeros((1, new_num_tokens - old_num_tokens), device=self.final_logits_bias.device) + new_bias = torch.cat([self.final_logits_bias, extra_bias], dim=1) + self.register_buffer("final_logits_bias", new_bias) + + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.LongTensor | None = None, + decoder_input_ids: torch.LongTensor | None = None, + decoder_attention_mask: torch.Tensor | None = None, + encoder_outputs: list[torch.FloatTensor] | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.FloatTensor | None = None, + decoder_inputs_embeds: torch.FloatTensor | None = None, + labels: torch.Tensor | None = None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + cache_position: torch.LongTensor | None = None, + **kwargs, + ) -> tuple[torch.Tensor] | Seq2SeqLMOutput: + r""" + decoder_input_ids (`torch.LongTensor` of shape `(batch_size, target_sequence_length)`, *optional*): + Indices of decoder input sequence tokens in the vocabulary. + + Indices can be obtained using [`AutoTokenizer`] or [`PLBartMultiTokenizer`] depending on the checkpoint. + See [`PreTrainedTokenizer.encode`] and [`PreTrainedTokenizer.__call__`] for details. + + [What are decoder input IDs?](../glossary#decoder-input-ids) + + PLBart uses a specific language id token as the starting token for `decoder_input_ids` generation that + varies according to source and target language, *e.g.* 50003 for *en_XX*, and 50001 for *java*. If + `past_key_values` is used, optionally only the last `decoder_input_ids` have to be input (see + `past_key_values`). + + For translation and summarization training, `decoder_input_ids` should be provided. If no + `decoder_input_ids` is provided, the model will create this tensor by shifting the `input_ids` to the right + for denoising pre-training following the paper. + decoder_attention_mask (: + obj:*torch.LongTensor* of shape `(batch_size, target_sequence_length)`, *optional*): + Default behavior: + generate a tensor that ignores pad tokens in `decoder_input_ids`. Causal mask will also be used by default. + labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Labels for computing the masked language modeling loss. Indices should either be in `[0, ..., + config.vocab_size]` or -100 (see `input_ids` docstring). Tokens with indices set to `-100` are ignored + (masked), the loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]`. + + Example Mask-filling: + + ```python + >>> from transformers import AutoTokenizer, PLBartForConditionalGeneration + + >>> model = PLBartForConditionalGeneration.from_pretrained("uclanlp/plbart-base") + >>> tokenizer = AutoTokenizer.from_pretrained("uclanlp/plbart-base") + + >>> # en_XX is the language symbol id for English + >>> TXT = " Is 0 the Fibonacci number ? en_XX" + >>> input_ids = tokenizer([TXT], add_special_tokens=False, return_tensors="pt").input_ids + + >>> logits = model(input_ids).logits + >>> masked_index = (input_ids[0] == tokenizer.mask_token_id).nonzero().item() + >>> probs = logits[0, masked_index].softmax(dim=0) + >>> values, predictions = probs.topk(5) + + >>> tokenizer.decode(predictions).split() + ['first', 'same', 'highest', 'result', 'number'] + ``` + """ + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + if labels is not None: + if decoder_input_ids is None and decoder_inputs_embeds is None: + decoder_input_ids = shift_tokens_right(labels, self.config.pad_token_id) + + outputs = self.model( + input_ids, + attention_mask=attention_mask, + decoder_input_ids=decoder_input_ids, + encoder_outputs=encoder_outputs, + decoder_attention_mask=decoder_attention_mask, + past_key_values=past_key_values, + inputs_embeds=inputs_embeds, + decoder_inputs_embeds=decoder_inputs_embeds, + use_cache=use_cache, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + cache_position=cache_position, + ) + lm_logits = self.lm_head(outputs[0]) + lm_logits = lm_logits + self.final_logits_bias.to(lm_logits.device) + + masked_lm_loss = None + if labels is not None: + loss_fct = CrossEntropyLoss() + masked_lm_loss = loss_fct(lm_logits.view(-1, self.config.vocab_size), labels.view(-1)) + + if not return_dict: + output = (lm_logits,) + outputs[1:] + return ((masked_lm_loss,) + output) if masked_lm_loss is not None else output + + return Seq2SeqLMOutput( + loss=masked_lm_loss, + logits=lm_logits, + past_key_values=outputs.past_key_values, + decoder_hidden_states=outputs.decoder_hidden_states, + decoder_attentions=outputs.decoder_attentions, + cross_attentions=outputs.cross_attentions, + encoder_last_hidden_state=outputs.encoder_last_hidden_state, + encoder_hidden_states=outputs.encoder_hidden_states, + encoder_attentions=outputs.encoder_attentions, + ) + + def prepare_decoder_input_ids_from_labels(self, labels: torch.Tensor): + return shift_tokens_right(labels, self.config.pad_token_id) + + +class PLBartClassificationHead(BartClassificationHead): + pass + + +class PLBartForSequenceClassification(BigBirdPegasusForSequenceClassification): + def forward(**super_kwargs): + r""" + decoder_input_ids (`torch.LongTensor` of shape `(batch_size, target_sequence_length)`, *optional*): + Indices of decoder input sequence tokens in the vocabulary. + + Indices can be obtained using [`AutoTokenizer`] or [`PLBartMultiTokenizer`] depending on the checkpoint. + See [`PreTrainedTokenizer.encode`] and [`PreTrainedTokenizer.__call__`] for details. + + [What are decoder input IDs?](../glossary#decoder-input-ids) + + PLBart uses a specific language id token as the starting token for `decoder_input_ids` generation that + varies according to source and target language, *e.g.* 50003 for *en_XX*, and 50001 for *java*. If + `past_key_values` is used, optionally only the last `decoder_input_ids` have to be input (see + `past_key_values`). + + For translation and summarization training, `decoder_input_ids` should be provided. If no + `decoder_input_ids` is provided, the model will create this tensor by shifting the `input_ids` to the right + for denoising pre-training following the paper. + decoder_attention_mask (: + obj:*torch.LongTensor* of shape `(batch_size, target_sequence_length)`, *optional*): + Default behavior: + generate a tensor that ignores pad tokens in `decoder_input_ids`. Causal mask will also be used by default. + labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*): + Labels for computing the sequence classification/regression loss. Indices should be in `[0, ..., + config.num_labels - 1]`. If `config.num_labels > 1` a classification loss is computed (Cross-Entropy). + """ + super().forward(**super_kwargs) + + +class PLBartForCausalLM(BartForCausalLM): + @auto_docstring + def forward(**super_kwargs): + r""" + labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Labels for computing the masked language modeling loss. Indices should either be in `[0, ..., + config.vocab_size]` or -100 (see `input_ids` docstring). Tokens with indices set to `-100` are ignored + (masked), the loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]`. + + Example: + + ```python + >>> from transformers import AutoTokenizer, PLBartForCausalLM + + >>> tokenizer = AutoTokenizer.from_pretrained("uclanlp/plbart-base") + >>> model = PLBartForCausalLM.from_pretrained("uclanlp/plbart-base") + >>> assert model.config.is_decoder, f"{model.__class__} has to be configured as a decoder." + >>> inputs = tokenizer("Hello, my dog is cute", return_tensors="pt") + >>> outputs = model(**inputs) + + >>> logits = outputs.logits + >>> expected_shape = [1, inputs.input_ids.shape[-1], model.config.vocab_size] + >>> list(logits.shape) == expected_shape + True + ```""" + super().forward(**super_kwargs) + + +__all__ = [ + "PLBartForCausalLM", + "PLBartForConditionalGeneration", + "PLBartForSequenceClassification", + "PLBartModel", + "PLBartPreTrainedModel", +] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/plbart/tokenization_plbart.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/plbart/tokenization_plbart.py new file mode 100644 index 0000000000000000000000000000000000000000..f848e25c24c7fbfc7ffb8ec334aed8d9a3e1e820 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/plbart/tokenization_plbart.py @@ -0,0 +1,347 @@ +# Copyright 2022, UCLA NLP, The Facebook AI Research Team Authors and The HuggingFace Inc. team. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +from typing import Any + +from ...tokenization_python import BatchEncoding +from ...tokenization_utils_base import AddedToken +from ...tokenization_utils_sentencepiece import SentencePieceBackend +from ...utils import logging +from ...utils.import_utils import requires + + +logger = logging.get_logger(__name__) + +SPIECE_UNDERLINE = "▁" + +VOCAB_FILES_NAMES = {"vocab_file": "sentencepiece.bpe.model", "tokenizer_file": "tokenizer.json"} + + +FAIRSEQ_LANGUAGE_CODES = { + "base": ["__java__", "__python__", "__en_XX__"], + "multi": ["__java__", "__python__", "__en_XX__", "__javascript__", "__php__", "__ruby__", "__go__"], +} + +FAIRSEQ_LANGUAGE_CODES_MAP = { + "java": "__java__", + "python": "__python__", + "en_XX": "__en_XX__", + "javascript": "__javascript__", + "php": "__php__", + "ruby": "__ruby__", + "go": "__go__", +} + + +@requires(backends=("sentencepiece",)) +class PLBartTokenizer(SentencePieceBackend): + """ + Construct an PLBART tokenizer. + + Adapted from [`RobertaTokenizer`] and [`XLNetTokenizer`]. Based on + [SentencePiece](https://github.com/google/sentencepiece). + + The tokenization method is ` ` for source language documents, and ` + ` for target language documents. + + Args: + vocab_file (`str`): + Path to the vocabulary file. + src_lang (`str`, *optional*): + A string representing the source language. + tgt_lang (`str`, *optional*): + A string representing the target language. + bos_token (`str`, *optional*, defaults to `""`): + The start of sequence token. + eos_token (`str`, *optional*, defaults to `""`): + The end of sequence token. + sep_token (`str`, *optional*, defaults to `""`): + The separator token, which is used when building a sequence from multiple sequences, e.g. two sequences for + sequence classification or for a text and a question for question answering. It is also used as the last + token of a sequence built with special tokens. + cls_token (`str`, *optional*, defaults to `""`): + The cls token, which is a special token used as the first token for all tasks. + unk_token (`str`, *optional*, defaults to `""`): + The unknown token. A token that is not in the vocabulary cannot be converted to an ID and is set to be this + token instead. + pad_token (`str`, *optional*, defaults to `""`): + The token used for padding, for example when batching sequences of different lengths. + mask_token(`str`, *optional*, defaults to `""`): + The token used for masking values. This is the token used when training this model with masking tasks. This + is only used in the `"base"` tokenizer type. For `"multi"` tokenizer, masking is never done for the + downstream tasks. + language_codes (`str`, *optional*, defaults to `"base"`): + What language codes to use. Should be one of `"base"` or `"multi"`. + sp_model_kwargs (`dict`, *optional*): + Will be passed to the `SentencePieceProcessor.__init__()` method. The [Python wrapper for + SentencePiece](https://github.com/google/sentencepiece/tree/master/python) can be used, among other things, + to set: + - `enable_sampling`: Enable subword regularization. + - `nbest_size`: Sampling parameters for unigram. Invalid for BPE-Dropout. + - `nbest_size = {0,1}`: No sampling is performed. + - `nbest_size > 1`: samples from the nbest_size results. + - `nbest_size < 0`: assuming that nbest_size is infinite and samples from the all hypothesis (lattice) + using forward-filtering-and-backward-sampling algorithm. + - `alpha`: Smoothing parameter for unigram sampling, and dropout probability of merge operations for + BPE-dropout. + + Examples: + + ```python + >>> from transformers import PLBartTokenizer + + >>> tokenizer = PLBartTokenizer.from_pretrained("uclanlp/plbart-python-en_XX", src_lang="python", tgt_lang="en_XX") + >>> example_python_phrase = "def maximum(a,b,c):NEW_LINE_INDENTreturn max([a,b,c])" + >>> expected_translation_english = "Returns the maximum value of a b c." + >>> inputs = tokenizer(example_python_phrase, text_target=expected_translation_english, return_tensors="pt") + ```""" + + vocab_files_names = VOCAB_FILES_NAMES + model_input_names = ["input_ids", "attention_mask"] + + prefix_tokens: list[int] = [] + suffix_tokens: list[int] = [] + + def __init__( + self, + vocab_file, + bos_token="", + eos_token="", + sep_token="", + cls_token="", + unk_token="", + pad_token="", + mask_token="", + language_codes="base", + src_lang=None, + tgt_lang=None, + sp_model_kwargs: dict[str, Any] | None = None, + additional_special_tokens=None, + clean_up_tokenization_spaces=True, + **kwargs, + ): + # Mask token behave like a normal word, i.e. include the space before it + mask_token = AddedToken(mask_token, lstrip=True, rstrip=False) if isinstance(mask_token, str) else mask_token + + self.sp_model_kwargs = {} if sp_model_kwargs is None else sp_model_kwargs + src_lang = self._convert_lang_code_special_format(src_lang) + tgt_lang = self._convert_lang_code_special_format(tgt_lang) + self.language_codes = language_codes + fairseq_language_codes = FAIRSEQ_LANGUAGE_CODES[self.language_codes] + + # Original fairseq vocab and spm vocab must be "aligned": + # Vocab | 0 | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 | 9 + # -------- | ------- | ------- | ------ | ------- | --- | --- | --- | ----- | ----- | ---- + # fairseq | '' | '' | '' | '' | ',' | '.' | '▁' | 's' | '▁de' | '-' + # spm | '' | '' | '' | ',' | '.' | '▁' | 's' | '▁de' | '-' | '▁a' + + # Mimic fairseq token-to-id alignment for the first 4 token + self.vocab_file = vocab_file + self.lang_code_to_id = {} + self.id_to_lang_code = {} + self.fairseq_tokens_to_ids = {"": 0, "": 1, "": 2, "": 3} + self.fairseq_ids_to_tokens = {v: k for k, v in self.fairseq_tokens_to_ids.items()} + self.fairseq_offset = 1 + _additional_special_tokens = list(fairseq_language_codes) + + if additional_special_tokens is not None: + _additional_special_tokens.extend( + [t for t in additional_special_tokens if t not in _additional_special_tokens] + ) + + super().__init__( + vocab_file=vocab_file, + bos_token=bos_token, + eos_token=eos_token, + unk_token=unk_token, + sep_token=sep_token, + cls_token=cls_token, + pad_token=pad_token, + mask_token=mask_token, + src_lang=src_lang, + tgt_lang=tgt_lang, + additional_special_tokens=_additional_special_tokens, + sp_model_kwargs=self.sp_model_kwargs, + clean_up_tokenization_spaces=clean_up_tokenization_spaces, + language_codes=language_codes, + special_tokens_pattern="prefix_suffix", + token_type_ids_pattern="all_zeros", + **kwargs, + ) + + # The first "real" token "," has position 4 in the original fairseq vocab and position 3 in the spm vocab + self.sp_model_size = len(self.sp_model) + self.lang_code_to_id = { + code: self.sp_model_size + i + self.fairseq_offset for i, code in enumerate(fairseq_language_codes) + } + self.id_to_lang_code = {v: k for k, v in self.lang_code_to_id.items()} + self.fairseq_tokens_to_ids = {"": 0, "": 1, "": 2, "": 3} + + if self.language_codes == "base": + self.fairseq_tokens_to_ids[""] = len(self.sp_model) + len(self.lang_code_to_id) + self.fairseq_offset + + self.fairseq_tokens_to_ids.update(self.lang_code_to_id) + self.fairseq_ids_to_tokens = {v: k for k, v in self.fairseq_tokens_to_ids.items()} + reserved_tokens = {"", "", "", "", ""} + reserved_tokens.update(FAIRSEQ_LANGUAGE_CODES[self.language_codes]) + + removed = False + for token in reserved_tokens: + idx = self._added_tokens_encoder.pop(token, None) + if idx is not None: + self._added_tokens_decoder.pop(idx, None) + removed = True + if removed: + self._update_trie() + self._update_total_vocab_size() + + synced = False + for token, idx in self._added_tokens_encoder.items(): + if idx in self._added_tokens_decoder: + continue + self._added_tokens_decoder[idx] = AddedToken( + token, special=True, normalized=False, lstrip=False, rstrip=False + ) + synced = True + if synced: + self._update_trie() + self._update_total_vocab_size() + + if self.language_codes == "base": + self._src_lang = src_lang + self.cur_lang_code_id = ( + self.lang_code_to_id[self._src_lang] if self._src_lang is not None else self._src_lang + ) + else: + self._src_lang = src_lang if src_lang is not None else "__en_XX__" + self.cur_lang_code_id = self.lang_code_to_id[self._src_lang] + + self.tgt_lang = tgt_lang + self.set_src_lang_special_tokens(self._src_lang) + + @property + def vocab_size(self): + lang_code_count = len(getattr(self, "lang_code_to_id", {})) + fairseq_offset = getattr(self, "fairseq_offset", 1) + base_vocab = len(self.sp_model) if hasattr(self, "sp_model") else 0 + if getattr(self, "language_codes", "base") == "base": + return base_vocab + lang_code_count + fairseq_offset + 1 # +1 for mask token + return base_vocab + lang_code_count + fairseq_offset + + def get_vocab(self): + """Override to use fairseq vocabulary structure""" + vocab = self.fairseq_tokens_to_ids.copy() + for i in range(self.sp_model.get_piece_size()): + sp_token = self.sp_model.IdToPiece(i) + # Map SP token to fairseq ID: SP ID 0 maps to unk_token_id, others map to SP_ID + fairseq_offset + vocab_id = self.unk_token_id if i == 0 else (i + self.fairseq_offset) + if sp_token not in vocab: + vocab[sp_token] = vocab_id + # Add any additional tokens + vocab.update({token: idx for token, idx in self._added_tokens_encoder.items() if token not in vocab}) + return vocab + + @property + def src_lang(self) -> str: + return self._src_lang + + @src_lang.setter + def src_lang(self, new_src_lang: str) -> None: + new_src_lang = self._convert_lang_code_special_format(new_src_lang) + self._src_lang = new_src_lang + self.set_src_lang_special_tokens(self._src_lang) + + def _build_translation_inputs( + self, raw_inputs, return_tensors: str, src_lang: str | None, tgt_lang: str | None, **extra_kwargs + ): + """Used by translation pipeline, to prepare inputs for the generate function""" + if src_lang is None or tgt_lang is None: + raise ValueError("Translation requires a `src_lang` and a `tgt_lang` for this model") + self.src_lang = self._convert_lang_code_special_format(src_lang) + self.tgt_lang = self._convert_lang_code_special_format(tgt_lang) + inputs = self(raw_inputs, add_special_tokens=True, return_tensors=return_tensors, **extra_kwargs) + tgt_lang_id = self.convert_tokens_to_ids(self.tgt_lang) + inputs["forced_bos_token_id"] = tgt_lang_id + return inputs + + def _convert_token_to_id(self, token): + """Converts a token (str) in an id using the vocab.""" + if token in self.fairseq_tokens_to_ids: + return self.fairseq_tokens_to_ids[token] + spm_id = self.sp_model.PieceToId(token) + + # Need to return unknown token if the SP model returned 0 + return spm_id + self.fairseq_offset if spm_id else self.unk_token_id + + def _convert_id_to_token(self, index): + """Converts an index (integer) in a token (str) using the vocab.""" + if index in self.fairseq_ids_to_tokens: + return self.fairseq_ids_to_tokens[index] + return self.sp_model.IdToPiece(index - self.fairseq_offset) + + def prepare_seq2seq_batch( + self, + src_texts: list[str], + src_lang: str = "en_XX", + tgt_texts: list[str] | None = None, + tgt_lang: str = "python", + **kwargs, + ) -> BatchEncoding: + self.src_lang = self._convert_lang_code_special_format(src_lang) + self.tgt_lang = self._convert_lang_code_special_format(tgt_lang) + return super().prepare_seq2seq_batch(src_texts, tgt_texts, **kwargs) + + def _switch_to_input_mode(self): + return self.set_src_lang_special_tokens(self.src_lang) + + def _switch_to_target_mode(self): + return self.set_tgt_lang_special_tokens(self.tgt_lang) + + def set_src_lang_special_tokens(self, src_lang) -> None: + """Reset the special tokens to the source lang setting. No prefix and suffix=[eos, src_lang_code].""" + src_lang = self._convert_lang_code_special_format(src_lang) + self.cur_lang_code = self.lang_code_to_id[src_lang] if src_lang is not None else None + self.prefix_tokens = [] + if self.cur_lang_code is not None: + self.suffix_tokens = [self.eos_token_id, self.cur_lang_code] + else: + self.suffix_tokens = [self.eos_token_id] + + def set_tgt_lang_special_tokens(self, lang: str) -> None: + """Reset the special tokens to the target language setting. No prefix and suffix=[eos, tgt_lang_code].""" + lang = self._convert_lang_code_special_format(lang) + + self.cur_lang_code = self.lang_code_to_id[lang] if lang is not None else None + self.prefix_tokens = [] + if self.cur_lang_code is not None: + self.suffix_tokens = [self.eos_token_id, self.cur_lang_code] + else: + self.suffix_tokens = [self.eos_token_id] + + def _convert_lang_code_special_format(self, lang: str) -> str: + """Convert Language Codes to format tokenizer uses if required""" + lang = FAIRSEQ_LANGUAGE_CODES_MAP.get(lang, lang) + return lang + + def decode(self, token_ids, skip_special_tokens=False, clean_up_tokenization_spaces=None, **kwargs): + """Override to use self.clean_up_tokenization_spaces as default for batched input.""" + return super().decode( + token_ids=token_ids, + skip_special_tokens=skip_special_tokens, + clean_up_tokenization_spaces=self.clean_up_tokenization_spaces, + **kwargs, + ) + + +__all__ = ["PLBartTokenizer"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/poolformer/__init__.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/poolformer/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..2e80bb47c302c88ffe33450d48a3b6ac6cf2ffc0 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/poolformer/__init__.py @@ -0,0 +1,30 @@ +# Copyright 2024 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from typing import TYPE_CHECKING + +from ...utils import _LazyModule +from ...utils.import_utils import define_import_structure + + +if TYPE_CHECKING: + from .configuration_poolformer import * + from .feature_extraction_poolformer import * + from .image_processing_poolformer import * + from .image_processing_poolformer_fast import * + from .modeling_poolformer import * +else: + import sys + + _file = globals()["__file__"] + sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__) diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/poolformer/configuration_poolformer.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/poolformer/configuration_poolformer.py new file mode 100644 index 0000000000000000000000000000000000000000..ec2974bd364b4586947be53f09ec1e7b1fe54acb --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/poolformer/configuration_poolformer.py @@ -0,0 +1,125 @@ +# Copyright 2022 Sea AI Labs and The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""PoolFormer model configuration""" + +from ...configuration_utils import PreTrainedConfig +from ...utils import logging + + +logger = logging.get_logger(__name__) + + +class PoolFormerConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of [`PoolFormerModel`]. It is used to instantiate a + PoolFormer model according to the specified arguments, defining the model architecture. Instantiating a + configuration with the defaults will yield a similar configuration to that of the PoolFormer + [sail/poolformer_s12](https://huggingface.co/sail/poolformer_s12) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + + Args: + num_channels (`int`, *optional*, defaults to 3): + The number of channels in the input image. + patch_size (`int`, *optional*, defaults to 16): + The size of the input patch. + stride (`int`, *optional*, defaults to 16): + The stride of the input patch. + pool_size (`int`, *optional*, defaults to 3): + The size of the pooling window. + mlp_ratio (`float`, *optional*, defaults to 4.0): + The ratio of the number of channels in the output of the MLP to the number of channels in the input. + depths (`list`, *optional*, defaults to `[2, 2, 6, 2]`): + The depth of each encoder block. + hidden_sizes (`list`, *optional*, defaults to `[64, 128, 320, 512]`): + The hidden sizes of each encoder block. + patch_sizes (`list`, *optional*, defaults to `[7, 3, 3, 3]`): + The size of the input patch for each encoder block. + strides (`list`, *optional*, defaults to `[4, 2, 2, 2]`): + The stride of the input patch for each encoder block. + padding (`list`, *optional*, defaults to `[2, 1, 1, 1]`): + The padding of the input patch for each encoder block. + num_encoder_blocks (`int`, *optional*, defaults to 4): + The number of encoder blocks. + drop_path_rate (`float`, *optional*, defaults to 0.0): + The dropout rate for the dropout layers. + hidden_act (`str`, *optional*, defaults to `"gelu"`): + The activation function for the hidden layers. + use_layer_scale (`bool`, *optional*, defaults to `True`): + Whether to use layer scale. + layer_scale_init_value (`float`, *optional*, defaults to 1e-05): + The initial value for the layer scale. + initializer_range (`float`, *optional*, defaults to 0.02): + The initializer range for the weights. + + Example: + + ```python + >>> from transformers import PoolFormerConfig, PoolFormerModel + + >>> # Initializing a PoolFormer sail/poolformer_s12 style configuration + >>> configuration = PoolFormerConfig() + + >>> # Initializing a model (with random weights) from the sail/poolformer_s12 style configuration + >>> model = PoolFormerModel(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ``` + """ + + model_type = "poolformer" + + def __init__( + self, + num_channels=3, + patch_size=16, + stride=16, + pool_size=3, + mlp_ratio=4.0, + depths=[2, 2, 6, 2], + hidden_sizes=[64, 128, 320, 512], + patch_sizes=[7, 3, 3, 3], + strides=[4, 2, 2, 2], + padding=[2, 1, 1, 1], + num_encoder_blocks=4, + drop_path_rate=0.0, + hidden_act="gelu", + use_layer_scale=True, + layer_scale_init_value=1e-5, + initializer_range=0.02, + **kwargs, + ): + self.num_channels = num_channels + self.patch_size = patch_size + self.stride = stride + self.padding = padding + self.pool_size = pool_size + self.hidden_sizes = hidden_sizes + self.mlp_ratio = mlp_ratio + self.depths = depths + self.patch_sizes = patch_sizes + self.strides = strides + self.num_encoder_blocks = num_encoder_blocks + self.drop_path_rate = drop_path_rate + self.hidden_act = hidden_act + self.use_layer_scale = use_layer_scale + self.layer_scale_init_value = layer_scale_init_value + self.initializer_range = initializer_range + super().__init__(**kwargs) + + +__all__ = ["PoolFormerConfig"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/poolformer/image_processing_poolformer.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/poolformer/image_processing_poolformer.py new file mode 100644 index 0000000000000000000000000000000000000000..47c0dc177a203d085713515a21527aae9f37338d --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/poolformer/image_processing_poolformer.py @@ -0,0 +1,363 @@ +# Copyright 2022 The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""Image processor class for PoolFormer.""" + +import numpy as np + +from ...image_processing_utils import BaseImageProcessor, BatchFeature, get_size_dict +from ...image_transforms import ( + get_resize_output_image_size, + resize, + to_channel_dimension_format, +) +from ...image_utils import ( + IMAGENET_DEFAULT_MEAN, + IMAGENET_DEFAULT_STD, + ChannelDimension, + ImageInput, + PILImageResampling, + infer_channel_dimension_format, + is_scaled_image, + make_flat_list_of_images, + to_numpy_array, + valid_images, + validate_preprocess_arguments, +) +from ...processing_utils import ImagesKwargs +from ...utils import TensorType, filter_out_non_signature_kwargs, is_vision_available, logging + + +if is_vision_available(): + import PIL + + +logger = logging.get_logger(__name__) + + +class PoolFormerImageProcessorKwargs(ImagesKwargs, total=False): + r""" + crop_pct (`float`, *optional*, defaults to `self.crop_pct`): + Percentage of the image to crop. Only has an effect if `do_resize` is set to `True`. + """ + + crop_pct: float + + +class PoolFormerImageProcessor(BaseImageProcessor): + r""" + Constructs a PoolFormer image processor. + + Args: + do_resize (`bool`, *optional*, defaults to `True`): + Whether to resize the image's (height, width) dimensions to the specified `size`. Can be overridden by + `do_resize` in the `preprocess` method. + size (`dict[str, int]` *optional*, defaults to `{"shortest_edge": 224}`): + Size of the image after resizing. Can be overridden by `size` in the `preprocess` method. If crop_pct is + unset: + - size is `{"height": h, "width": w}`: the image is resized to `(h, w)`. + - size is `{"shortest_edge": s}`: the shortest edge of the image is resized to s whilst maintaining the + aspect ratio. + + If crop_pct is set: + - size is `{"height": h, "width": w}`: the image is resized to `(int(floor(h/crop_pct)), + int(floor(w/crop_pct)))` + - size is `{"height": c, "width": c}`: the shortest edge of the image is resized to `int(floor(c/crop_pct)` + whilst maintaining the aspect ratio. + - size is `{"shortest_edge": c}`: the shortest edge of the image is resized to `int(floor(c/crop_pct)` + whilst maintaining the aspect ratio. + crop_pct (`float`, *optional*, defaults to 0.9): + Percentage of the image to crop from the center. Can be overridden by `crop_pct` in the `preprocess` + method. + resample (`PILImageResampling`, *optional*, defaults to `Resampling.BICUBIC`): + Resampling filter to use if resizing the image. Can be overridden by `resample` in the `preprocess` method. + do_center_crop (`bool`, *optional*, defaults to `True`): + Whether to center crop the image. If the input size is smaller than `crop_size` along any edge, the image + is padded with 0's and then center cropped. Can be overridden by `do_center_crop` in the `preprocess` + method. + crop_size (`dict[str, int]`, *optional*, defaults to `{"height": 224, "width": 224}`): + Size of the image after applying center crop. Only has an effect if `do_center_crop` is set to `True`. Can + be overridden by the `crop_size` parameter in the `preprocess` method. + rescale_factor (`int` or `float`, *optional*, defaults to `1/255`): + Scale factor to use if rescaling the image. Can be overridden by the `rescale_factor` parameter in the + `preprocess` method. + do_rescale (`bool`, *optional*, defaults to `True`): + Whether to rescale the image by the specified scale `rescale_factor`. Can be overridden by the `do_rescale` + parameter in the `preprocess` method. + do_normalize (`bool`, *optional*, defaults to `True`): + Controls whether to normalize the image. Can be overridden by the `do_normalize` parameter in the + `preprocess` method. + image_mean (`float` or `list[float]`, *optional*, defaults to `IMAGENET_STANDARD_MEAN`): + Mean to use if normalizing the image. This is a float or list of floats the length of the number of + channels in the image. Can be overridden by the `image_mean` parameter in the `preprocess` method. + image_std (`float` or `list[float]`, *optional*, defaults to `IMAGENET_STANDARD_STD`): + Standard deviation to use if normalizing the image. This is a float or list of floats the length of the + number of channels in the image. Can be overridden by the `image_std` parameter in the `preprocess` method. + """ + + model_input_names = ["pixel_values"] + valid_kwargs = PoolFormerImageProcessorKwargs + + def __init__( + self, + do_resize: bool = True, + size: dict[str, int] | None = None, + crop_pct: int = 0.9, + resample: PILImageResampling = PILImageResampling.BICUBIC, + do_center_crop: bool = True, + crop_size: dict[str, int] | None = None, + rescale_factor: int | float = 1 / 255, + do_rescale: bool = True, + do_normalize: bool = True, + image_mean: float | list[float] | None = None, + image_std: float | list[float] | None = None, + **kwargs, + ) -> None: + super().__init__(**kwargs) + size = size if size is not None else {"shortest_edge": 224} + size = get_size_dict(size, default_to_square=False) + crop_size = crop_size if crop_size is not None else {"height": 224, "width": 224} + crop_size = get_size_dict(crop_size, param_name="crop_size") + + self.do_resize = do_resize + self.size = size + self.crop_pct = crop_pct + self.resample = resample + self.do_center_crop = do_center_crop + self.crop_size = crop_size + self.do_rescale = do_rescale + self.rescale_factor = rescale_factor + self.do_normalize = do_normalize + self.image_mean = image_mean if image_mean is not None else IMAGENET_DEFAULT_MEAN + self.image_std = image_std if image_std is not None else IMAGENET_DEFAULT_STD + + def resize( + self, + image: np.ndarray, + size: dict[str, int], + crop_pct: float | None = None, + resample: PILImageResampling = PILImageResampling.BICUBIC, + data_format: str | ChannelDimension | None = None, + input_data_format: str | ChannelDimension | None = None, + **kwargs, + ) -> np.ndarray: + """ + Resize an image. + + If crop_pct is unset: + - size is `{"height": h, "width": w}`: the image is resized to `(h, w)`. + - size is `{"shortest_edge": s}`: the shortest edge of the image is resized to s whilst maintaining the + aspect ratio. + + if crop_pct is set: + - size is `{"height": h, "width": w}`: the image is resized to `(int(floor(h/crop_pct)), + int(floor(w/crop_pct)))` + - size is `{"height": c, "width": c}`: the shortest edge of the image is resized to `int(floor(c/crop_pct)` + whilst maintaining the aspect ratio. + - size is `{"shortest_edge": c}`: the shortest edge of the image is resized to `int(floor(c/crop_pct)` + whilst maintaining the aspect ratio. + + Args: + image (`np.ndarray`): + Image to resize. + size (`dict[str, int]`): + Size of the output image. + crop_pct (`float`, *optional*): + Percentage of the image that will be cropped from the center. If set, the image is resized + resample (`PILImageResampling`, *optional*, defaults to `PILImageResampling.BICUBIC`): + Resampling filter to use when resizing the image. + data_format (`str` or `ChannelDimension`, *optional*): + The channel dimension format of the image. If not provided, it will be the same as the input image. + input_data_format (`str` or `ChannelDimension`, *optional*): + The channel dimension format of the input image. If not provided, it will be inferred. + """ + size = get_size_dict(size, default_to_square=False) + if "shortest_edge" not in size and ("height" not in size or "width" not in size): + raise ValueError(f"size must contain 'height' and 'width' or 'shortest_edge' as keys. Got {size.keys()}") + if crop_pct is not None: + if "shortest_edge" in size: + scale_size = int(size["shortest_edge"] / crop_pct) + elif "height" in size and "width" in size: + if size["height"] == size["width"]: + scale_size = int(size["height"] / crop_pct) + else: + scale_size = (int(size["height"] / crop_pct), int(size["width"] / crop_pct)) + else: + raise ValueError(f"Invalid size for resize: {size}") + + output_size = get_resize_output_image_size( + image, size=scale_size, default_to_square=False, input_data_format=input_data_format + ) + else: + if "shortest_edge" in size: + output_size = get_resize_output_image_size( + image, size=size["shortest_edge"], default_to_square=False, input_data_format=input_data_format + ) + elif "height" in size and "width" in size: + output_size = (size["height"], size["width"]) + else: + raise ValueError(f"Invalid size for resize: {size}") + + return resize( + image, + size=output_size, + resample=resample, + data_format=data_format, + input_data_format=input_data_format, + **kwargs, + ) + + @filter_out_non_signature_kwargs() + def preprocess( + self, + images: ImageInput, + do_resize: bool | None = None, + size: dict[str, int] | None = None, + crop_pct: int | None = None, + resample: PILImageResampling | None = None, + do_center_crop: bool | None = None, + crop_size: dict[str, int] | None = None, + do_rescale: bool | None = None, + rescale_factor: float | None = None, + do_normalize: bool | None = None, + image_mean: float | list[float] | None = None, + image_std: float | list[float] | None = None, + return_tensors: str | TensorType | None = None, + data_format: ChannelDimension = ChannelDimension.FIRST, + input_data_format: str | ChannelDimension | None = None, + ) -> PIL.Image.Image: + """ + Preprocess an image or batch of images. + + Args: + images (`ImageInput`): + Image to preprocess. Expects a single or batch of images with pixel values ranging from 0 to 255. If + passing in images with pixel values between 0 and 1, set `do_rescale=False`. + do_resize (`bool`, *optional*, defaults to `self.do_resize`): + Whether to resize the image. + size (`dict[str, int]`, *optional*, defaults to `self.size`): + Size of the image after applying resize. + crop_pct (`float`, *optional*, defaults to `self.crop_pct`): + Percentage of the image to crop. Only has an effect if `do_resize` is set to `True`. + resample (`int`, *optional*, defaults to `self.resample`): + Resampling filter to use if resizing the image. This can be one of the enum `PILImageResampling`, Only + has an effect if `do_resize` is set to `True`. + do_center_crop (`bool`, *optional*, defaults to `self.do_center_crop`): + Whether to center crop the image. + crop_size (`dict[str, int]`, *optional*, defaults to `self.crop_size`): + Size of the image after applying center crop. + do_rescale (`bool`, *optional*, defaults to `self.do_rescale`): + Whether to rescale the image values between [0 - 1]. + rescale_factor (`float`, *optional*, defaults to `self.rescale_factor`): + Rescale factor to rescale the image by if `do_rescale` is set to `True`. + do_normalize (`bool`, *optional*, defaults to `self.do_normalize`): + Whether to normalize the image. + image_mean (`float` or `list[float]`, *optional*, defaults to `self.image_mean`): + Image mean. + image_std (`float` or `list[float]`, *optional*, defaults to `self.image_std`): + Image standard deviation. + return_tensors (`str` or `TensorType`, *optional*): + The type of tensors to return. Can be one of: + - Unset: Return a list of `np.ndarray`. + - `TensorType.PYTORCH` or `'pt'`: Return a batch of type `torch.Tensor`. + - `TensorType.NUMPY` or `'np'`: Return a batch of type `np.ndarray`. + data_format (`ChannelDimension` or `str`, *optional*, defaults to `ChannelDimension.FIRST`): + The channel dimension format for the output image. Can be one of: + - `ChannelDimension.FIRST`: image in (num_channels, height, width) format. + - `ChannelDimension.LAST`: image in (height, width, num_channels) format. + input_data_format (`ChannelDimension` or `str`, *optional*): + The channel dimension format for the input image. If unset, the channel dimension format is inferred + from the input image. Can be one of: + - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format. + - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format. + - `"none"` or `ChannelDimension.NONE`: image in (height, width) format. + """ + do_resize = do_resize if do_resize is not None else self.do_resize + crop_pct = crop_pct if crop_pct is not None else self.crop_pct + resample = resample if resample is not None else self.resample + do_center_crop = do_center_crop if do_center_crop is not None else self.do_center_crop + do_rescale = do_rescale if do_rescale is not None else self.do_rescale + rescale_factor = rescale_factor if rescale_factor is not None else self.rescale_factor + do_normalize = do_normalize if do_normalize is not None else self.do_normalize + image_mean = image_mean if image_mean is not None else self.image_mean + image_std = image_std if image_std is not None else self.image_std + + size = size if size is not None else self.size + size = get_size_dict(size, default_to_square=False) + crop_size = crop_size if crop_size is not None else self.crop_size + crop_size = get_size_dict(crop_size, param_name="crop_size") + + images = make_flat_list_of_images(images) + + if not valid_images(images): + raise ValueError("Invalid image type. Must be of type PIL.Image.Image, numpy.ndarray, or torch.Tensor") + validate_preprocess_arguments( + do_rescale=do_rescale, + rescale_factor=rescale_factor, + do_normalize=do_normalize, + image_mean=image_mean, + image_std=image_std, + do_center_crop=do_center_crop, + crop_size=crop_size, + do_resize=do_resize, + size=size, + resample=resample, + ) + + # All transformations expect numpy arrays. + images = [to_numpy_array(image) for image in images] + + if do_rescale and is_scaled_image(images[0]): + logger.warning_once( + "It looks like you are trying to rescale already rescaled images. If the input" + " images have pixel values between 0 and 1, set `do_rescale=False` to avoid rescaling them again." + ) + + if input_data_format is None: + # We assume that all images have the same channel dimension format. + input_data_format = infer_channel_dimension_format(images[0]) + + if do_resize: + images = [ + self.resize( + image=image, size=size, crop_pct=crop_pct, resample=resample, input_data_format=input_data_format + ) + for image in images + ] + + if do_center_crop: + images = [ + self.center_crop(image=image, size=crop_size, input_data_format=input_data_format) for image in images + ] + + if do_rescale: + images = [ + self.rescale(image=image, scale=rescale_factor, input_data_format=input_data_format) + for image in images + ] + + if do_normalize: + images = [ + self.normalize(image=image, mean=image_mean, std=image_std, input_data_format=input_data_format) + for image in images + ] + + images = [ + to_channel_dimension_format(image, data_format, input_channel_dim=input_data_format) for image in images + ] + + data = {"pixel_values": images} + return BatchFeature(data=data, tensor_type=return_tensors) + + +__all__ = ["PoolFormerImageProcessor"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/poolformer/image_processing_poolformer_fast.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/poolformer/image_processing_poolformer_fast.py new file mode 100644 index 0000000000000000000000000000000000000000..fc55ff6b914f3a4e1da945968dea44cc58a752bb --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/poolformer/image_processing_poolformer_fast.py @@ -0,0 +1,237 @@ +# Copyright 2025 The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""Fast Image processor class for PoolFormer.""" + +from typing import Optional + +import torch +import torchvision.transforms.v2.functional as tvF + +from ...image_processing_utils_fast import BaseImageProcessorFast, BatchFeature +from ...image_transforms import ( + ChannelDimension, + get_resize_output_image_size, + get_size_with_aspect_ratio, + group_images_by_shape, + reorder_images, +) +from ...image_utils import ( + IMAGENET_DEFAULT_MEAN, + IMAGENET_DEFAULT_STD, + ImageInput, + PILImageResampling, + SizeDict, + get_image_size_for_max_height_width, +) +from ...processing_utils import Unpack +from ...utils import ( + TensorType, + auto_docstring, +) +from .image_processing_poolformer import PoolFormerImageProcessorKwargs + + +@auto_docstring +class PoolFormerImageProcessorFast(BaseImageProcessorFast): + resample = PILImageResampling.BICUBIC + image_mean = IMAGENET_DEFAULT_MEAN + image_std = IMAGENET_DEFAULT_STD + size = {"shortest_edge": 224} + default_to_square = False + crop_size = {"height": 224, "width": 224} + crop_pct = 0.9 + do_resize = True + do_center_crop = True + do_rescale = True + do_normalize = True + valid_kwargs = PoolFormerImageProcessorKwargs + + def __init__(self, **kwargs: Unpack[PoolFormerImageProcessorKwargs]): + super().__init__(**kwargs) + + @auto_docstring + def preprocess(self, images: ImageInput, **kwargs: Unpack[PoolFormerImageProcessorKwargs]) -> BatchFeature: + return super().preprocess(images, **kwargs) + + def resize( + self, + image: "torch.Tensor", + size: SizeDict, + crop_pct: float | None = None, + interpolation: Optional["tvF.InterpolationMode"] = None, + antialias: bool = True, + **kwargs, + ) -> "torch.Tensor": + """ + Resize an image. + + If crop_pct is unset: + - size is `{"height": h, "width": w}`: the image is resized to `(h, w)`. + - size is `{"shortest_edge": s}`: the shortest edge of the image is resized to s whilst maintaining the + aspect ratio. + + if crop_pct is set: + - size is `{"height": h, "width": w}`: the image is resized to `(int(floor(h/crop_pct)), + int(floor(w/crop_pct)))` + - size is `{"height": c, "width": c}`: the shortest edge of the image is resized to `int(floor(c/crop_pct)` + whilst maintaining the aspect ratio. + - size is `{"shortest_edge": c}`: the shortest edge of the image is resized to `int(floor(c/crop_pct)` + whilst maintaining the aspect ratio. + + Args: + image (`torch.Tensor`): + Image to resize. + size (`SizeDict`): + Dictionary in the format `{"height": int, "width": int}` specifying the size of the output image. + crop_pct (`float`, *optional*): + Percentage of the image that will be cropped from the center. If set, the image is resized + resample (`InterpolationMode`, *optional*, defaults to `InterpolationMode.BILINEAR`): + `InterpolationMode` filter to use when resizing the image e.g. `InterpolationMode.BICUBIC`. + + Returns: + `torch.Tensor`: The resized image. + """ + interpolation = interpolation if interpolation is not None else tvF.InterpolationMode.BILINEAR + if crop_pct is not None: + if size.shortest_edge: + scale_size = int(size.shortest_edge / crop_pct) + elif size.height and size.width: + if size.height == size.width: + scale_size = int(size.height / crop_pct) + else: + scale_size = (int(size.height / crop_pct), int(size.width / crop_pct)) + else: + raise ValueError(f"Invalid size for resize: {size}") + + new_size = get_resize_output_image_size( + image, + size=scale_size, + default_to_square=False, + input_data_format=ChannelDimension.FIRST, + ) + else: + if size.shortest_edge and size.longest_edge: + # Resize the image so that the shortest edge or the longest edge is of the given size + # while maintaining the aspect ratio of the original image. + new_size = get_size_with_aspect_ratio( + image.size()[-2:], + size.shortest_edge, + size.longest_edge, + ) + elif size.shortest_edge: + new_size = get_resize_output_image_size( + image, + size=size.shortest_edge, + default_to_square=False, + input_data_format=ChannelDimension.FIRST, + ) + elif size.max_height and size.max_width: + new_size = get_image_size_for_max_height_width(image.size()[-2:], size.max_height, size.max_width) + elif size.height and size.width: + new_size = (size.height, size.width) + else: + raise ValueError( + "Size must contain 'height' and 'width' keys, or 'max_height' and 'max_width', or 'shortest_edge' key. Got" + f" {size}." + ) + return tvF.resize(image, new_size, interpolation=interpolation, antialias=antialias) + + def center_crop( + self, + image: "torch.Tensor", + size: SizeDict, + **kwargs, + ) -> "torch.Tensor": + """ + Center crop an image to `(size["height"], size["width"])`. If the input size is smaller than `crop_size` along + any edge, the image is padded with 0's and then center cropped. + + Args: + image (`"torch.Tensor"`): + Image to center crop. + size (`dict[str, int]`): + Size of the output image. + + Returns: + `torch.Tensor`: The center cropped image. + """ + if size.height is None or size.width is None: + raise ValueError(f"The size dictionary must have keys 'height' and 'width'. Got {size.keys()}") + image_height, image_width = image.shape[-2:] + crop_height, crop_width = size.height, size.width + + if crop_width > image_width or crop_height > image_height: + padding_ltrb = [ + (crop_width - image_width) // 2 if crop_width > image_width else 0, + (crop_height - image_height) // 2 if crop_height > image_height else 0, + (crop_width - image_width + 1) // 2 if crop_width > image_width else 0, + (crop_height - image_height + 1) // 2 if crop_height > image_height else 0, + ] + image = tvF.pad(image, padding_ltrb, fill=0) # PIL uses fill value 0 + image_height, image_width = image.shape[-2:] + if crop_width == image_width and crop_height == image_height: + return image + + crop_top = int((image_height - crop_height) / 2.0) + crop_left = int((image_width - crop_width) / 2.0) + return tvF.crop(image, crop_top, crop_left, crop_height, crop_width) + + def _preprocess( + self, + images: list["torch.Tensor"], + do_resize: bool, + size: SizeDict, + crop_pct: float, + interpolation: Optional["tvF.InterpolationMode"], + do_center_crop: bool, + crop_size: SizeDict, + do_rescale: bool, + rescale_factor: float, + do_normalize: bool, + image_mean: float | list[float] | None, + image_std: float | list[float] | None, + disable_grouping: bool | None, + return_tensors: str | TensorType | None, + **kwargs, + ) -> BatchFeature: + # Group images by size for batched resizing + grouped_images, grouped_images_index = group_images_by_shape(images, disable_grouping=disable_grouping) + resized_images_grouped = {} + for shape, stacked_images in grouped_images.items(): + if do_resize: + stacked_images = self.resize( + image=stacked_images, size=size, crop_pct=crop_pct, interpolation=interpolation + ) + resized_images_grouped[shape] = stacked_images + resized_images = reorder_images(resized_images_grouped, grouped_images_index) + + # Group images by size for further processing + # Needed in case do_resize is False, or resize returns images with different sizes + grouped_images, grouped_images_index = group_images_by_shape(resized_images, disable_grouping=disable_grouping) + processed_images_grouped = {} + for shape, stacked_images in grouped_images.items(): + if do_center_crop: + stacked_images = self.center_crop(stacked_images, crop_size) + # Fused rescale and normalize + stacked_images = self.rescale_and_normalize( + stacked_images, do_rescale, rescale_factor, do_normalize, image_mean, image_std + ) + processed_images_grouped[shape] = stacked_images + + processed_images = reorder_images(processed_images_grouped, grouped_images_index) + + return BatchFeature(data={"pixel_values": processed_images}, tensor_type=return_tensors) + + +__all__ = ["PoolFormerImageProcessorFast"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/poolformer/modeling_poolformer.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/poolformer/modeling_poolformer.py new file mode 100644 index 0000000000000000000000000000000000000000..52f8e4843ab903d176b9ac59a95ff633b0e5201b --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/poolformer/modeling_poolformer.py @@ -0,0 +1,382 @@ +# Copyright 2022 Sea AI Lab and The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""PyTorch PoolFormer model.""" + +import collections.abc + +import torch +from torch import nn + +from ... import initialization as init +from ...activations import ACT2FN +from ...modeling_outputs import BaseModelOutputWithNoAttention, ImageClassifierOutputWithNoAttention +from ...modeling_utils import PreTrainedModel +from ...utils import auto_docstring, logging +from .configuration_poolformer import PoolFormerConfig + + +logger = logging.get_logger(__name__) + + +# Copied from transformers.models.beit.modeling_beit.drop_path +def drop_path(input: torch.Tensor, drop_prob: float = 0.0, training: bool = False) -> torch.Tensor: + """ + Drop paths (Stochastic Depth) per sample (when applied in main path of residual blocks). + + """ + if drop_prob == 0.0 or not training: + return input + keep_prob = 1 - drop_prob + shape = (input.shape[0],) + (1,) * (input.ndim - 1) # work with diff dim tensors, not just 2D ConvNets + random_tensor = keep_prob + torch.rand(shape, dtype=input.dtype, device=input.device) + random_tensor.floor_() # binarize + output = input.div(keep_prob) * random_tensor + return output + + +# Copied from transformers.models.beit.modeling_beit.BeitDropPath with Beit->PoolFormer +class PoolFormerDropPath(nn.Module): + """Drop paths (Stochastic Depth) per sample (when applied in main path of residual blocks).""" + + def __init__(self, drop_prob: float | None = None) -> None: + super().__init__() + self.drop_prob = drop_prob + + def forward(self, hidden_states: torch.Tensor) -> torch.Tensor: + return drop_path(hidden_states, self.drop_prob, self.training) + + def extra_repr(self) -> str: + return f"p={self.drop_prob}" + + +class PoolFormerEmbeddings(nn.Module): + """ + Construct Patch Embeddings. + """ + + def __init__(self, hidden_size, num_channels, patch_size, stride, padding, norm_layer=None): + super().__init__() + patch_size = patch_size if isinstance(patch_size, collections.abc.Iterable) else (patch_size, patch_size) + stride = stride if isinstance(stride, collections.abc.Iterable) else (stride, stride) + padding = padding if isinstance(padding, collections.abc.Iterable) else (padding, padding) + + self.projection = nn.Conv2d(num_channels, hidden_size, kernel_size=patch_size, stride=stride, padding=padding) + self.norm = norm_layer(hidden_size) if norm_layer else nn.Identity() + + def forward(self, pixel_values): + embeddings = self.projection(pixel_values) + embeddings = self.norm(embeddings) + return embeddings + + +class PoolFormerGroupNorm(nn.GroupNorm): + """ + Group Normalization with 1 group. Input: tensor in shape [B, C, H, W] + """ + + def __init__(self, num_channels, **kwargs): + super().__init__(1, num_channels, **kwargs) + + +class PoolFormerPooling(nn.Module): + def __init__(self, pool_size): + super().__init__() + self.pool = nn.AvgPool2d(pool_size, stride=1, padding=pool_size // 2, count_include_pad=False) + + def forward(self, hidden_states): + return self.pool(hidden_states) - hidden_states + + +class PoolFormerOutput(nn.Module): + def __init__(self, config, dropout_prob, hidden_size, intermediate_size): + super().__init__() + self.conv1 = nn.Conv2d(hidden_size, intermediate_size, 1) + self.conv2 = nn.Conv2d(intermediate_size, hidden_size, 1) + self.drop = PoolFormerDropPath(dropout_prob) + if isinstance(config.hidden_act, str): + self.act_fn = ACT2FN[config.hidden_act] + else: + self.act_fn = config.hidden_act + + def forward(self, hidden_states): + hidden_states = self.conv1(hidden_states) + hidden_states = self.act_fn(hidden_states) + hidden_states = self.drop(hidden_states) + hidden_states = self.conv2(hidden_states) + hidden_states = self.drop(hidden_states) + + return hidden_states + + +class PoolFormerLayer(nn.Module): + """This corresponds to the 'PoolFormerBlock' class in the original implementation.""" + + def __init__(self, config, num_channels, pool_size, hidden_size, intermediate_size, drop_path): + super().__init__() + self.pooling = PoolFormerPooling(pool_size) + self.output = PoolFormerOutput(config, drop_path, hidden_size, intermediate_size) + self.before_norm = PoolFormerGroupNorm(num_channels) + self.after_norm = PoolFormerGroupNorm(num_channels) + + # Useful for training neural nets + self.drop_path = PoolFormerDropPath(drop_path) if drop_path > 0.0 else nn.Identity() + self.use_layer_scale = config.use_layer_scale + if config.use_layer_scale: + self.layer_scale_1 = nn.Parameter( + config.layer_scale_init_value * torch.ones(num_channels), requires_grad=True + ) + self.layer_scale_2 = nn.Parameter( + config.layer_scale_init_value * torch.ones(num_channels), requires_grad=True + ) + + def forward(self, hidden_states): + if self.use_layer_scale: + pooling_output = self.pooling(self.before_norm(hidden_states)) + scaled_op = self.layer_scale_1.unsqueeze(-1).unsqueeze(-1) * pooling_output + # First residual connection + hidden_states = hidden_states + self.drop_path(scaled_op) + outputs = () + + layer_output = self.output(self.after_norm(hidden_states)) + scaled_op = self.layer_scale_2.unsqueeze(-1).unsqueeze(-1) * layer_output + # Second residual connection + output = hidden_states + self.drop_path(scaled_op) + + outputs = (output,) + outputs + return outputs + + else: + pooling_output = self.drop_path(self.pooling(self.before_norm(hidden_states))) + # First residual connection + hidden_states = pooling_output + hidden_states + outputs = () + + # Second residual connection inside the PoolFormerOutput block + layer_output = self.drop_path(self.output(self.after_norm(hidden_states))) + output = hidden_states + layer_output + + outputs = (output,) + outputs + return outputs + + +class PoolFormerEncoder(nn.Module): + def __init__(self, config): + super().__init__() + self.config = config + # stochastic depth decay rule + dpr = [x.item() for x in torch.linspace(0, config.drop_path_rate, sum(config.depths), device="cpu")] + + # patch embeddings + embeddings = [] + for i in range(config.num_encoder_blocks): + embeddings.append( + PoolFormerEmbeddings( + patch_size=config.patch_sizes[i], + stride=config.strides[i], + padding=config.padding[i], + num_channels=config.num_channels if i == 0 else config.hidden_sizes[i - 1], + hidden_size=config.hidden_sizes[i], + ) + ) + self.patch_embeddings = nn.ModuleList(embeddings) + + # Transformer blocks + blocks = [] + cur = 0 + for i in range(config.num_encoder_blocks): + # each block consists of layers + layers = [] + if i != 0: + cur += config.depths[i - 1] + for j in range(config.depths[i]): + layers.append( + PoolFormerLayer( + config, + num_channels=config.hidden_sizes[i], + pool_size=config.pool_size, + hidden_size=config.hidden_sizes[i], + intermediate_size=int(config.hidden_sizes[i] * config.mlp_ratio), + drop_path=dpr[cur + j], + ) + ) + blocks.append(nn.ModuleList(layers)) + + self.block = nn.ModuleList(blocks) + + def forward(self, pixel_values, output_hidden_states=False, return_dict=True): + all_hidden_states = () if output_hidden_states else None + + hidden_states = pixel_values + for idx, layers in enumerate(zip(self.patch_embeddings, self.block)): + embedding_layer, block_layer = layers + # Get patch embeddings from hidden_states + hidden_states = embedding_layer(hidden_states) + # Send the embeddings through the blocks + for _, blk in enumerate(block_layer): + layer_outputs = blk(hidden_states) + hidden_states = layer_outputs[0] + + if output_hidden_states: + all_hidden_states = all_hidden_states + (hidden_states,) + + if not return_dict: + return tuple(v for v in [hidden_states, all_hidden_states] if v is not None) + + return BaseModelOutputWithNoAttention(last_hidden_state=hidden_states, hidden_states=all_hidden_states) + + +@auto_docstring +class PoolFormerPreTrainedModel(PreTrainedModel): + config: PoolFormerConfig + base_model_prefix = "poolformer" + main_input_name = "pixel_values" + input_modalities = ("image",) + _no_split_modules = ["PoolFormerLayer"] + + @torch.no_grad() + def _init_weights(self, module): + """Initialize the weights""" + super()._init_weights(module) + if isinstance(module, PoolFormerLayer): + if hasattr(module, "layer_scale_1"): + init.constant_(module.layer_scale_1, self.config.layer_scale_init_value) + init.constant_(module.layer_scale_2, self.config.layer_scale_init_value) + + +@auto_docstring +class PoolFormerModel(PoolFormerPreTrainedModel): + def __init__(self, config): + super().__init__(config) + self.config = config + + self.encoder = PoolFormerEncoder(config) + + # Initialize weights and apply final processing + self.post_init() + + def get_input_embeddings(self): + # Input embeddings correspond to the very first patch-embedding stage. + return self.encoder.patch_embeddings[0] + + def set_input_embeddings(self, value): + self.encoder.patch_embeddings[0] = value + + @auto_docstring + def forward( + self, + pixel_values: torch.FloatTensor | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + **kwargs, + ) -> tuple | BaseModelOutputWithNoAttention: + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + if pixel_values is None: + raise ValueError("You have to specify pixel_values") + + encoder_outputs = self.encoder( + pixel_values, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + sequence_output = encoder_outputs[0] + + if not return_dict: + return (sequence_output, None) + encoder_outputs[1:] + + return BaseModelOutputWithNoAttention( + last_hidden_state=sequence_output, + hidden_states=encoder_outputs.hidden_states, + ) + + +class PoolFormerFinalPooler(nn.Module): + def __init__(self, config): + super().__init__() + self.dense = nn.Linear(config.hidden_size, config.hidden_size) + + def forward(self, hidden_states): + output = self.dense(hidden_states) + return output + + +@auto_docstring( + custom_intro=""" + PoolFormer Model transformer with an image classification head on top + """ +) +class PoolFormerForImageClassification(PoolFormerPreTrainedModel): + def __init__(self, config): + super().__init__(config) + self.num_labels = config.num_labels + self.poolformer = PoolFormerModel(config) + + # Final norm + self.norm = PoolFormerGroupNorm(config.hidden_sizes[-1]) + # Classifier head + self.classifier = ( + nn.Linear(config.hidden_sizes[-1], config.num_labels) if config.num_labels > 0 else nn.Identity() + ) + + # Initialize weights and apply final processing + self.post_init() + + def get_input_embeddings(self): + return self.poolformer.get_input_embeddings() + + def set_input_embeddings(self, value): + self.poolformer.set_input_embeddings(value) + + @auto_docstring + def forward( + self, + pixel_values: torch.FloatTensor | None = None, + labels: torch.LongTensor | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + **kwargs, + ) -> tuple | ImageClassifierOutputWithNoAttention: + r""" + labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*): + Labels for computing the image classification/regression loss. Indices should be in `[0, ..., + config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If + `config.num_labels > 1` a classification loss is computed (Cross-Entropy). + """ + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + outputs = self.poolformer( + pixel_values, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + + sequence_output = outputs[0] + + logits = self.classifier(self.norm(sequence_output).mean([-2, -1])) + + loss = None + if labels is not None: + loss = self.loss_function(labels, logits, self.config) + + if not return_dict: + output = (logits,) + outputs[2:] + return ((loss,) + output) if loss is not None else output + + return ImageClassifierOutputWithNoAttention(loss=loss, logits=logits, hidden_states=outputs.hidden_states) + + +__all__ = ["PoolFormerForImageClassification", "PoolFormerModel", "PoolFormerPreTrainedModel"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pop2piano/__init__.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pop2piano/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..cbbfcbf157b58aa582e2a8b2a99c7d561372904b --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pop2piano/__init__.py @@ -0,0 +1,27 @@ +# Copyright 2024 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from typing import TYPE_CHECKING + +from ...utils import _LazyModule +from ...utils.import_utils import define_import_structure + + +if TYPE_CHECKING: + from .configuration_pop2piano import * + from .modeling_pop2piano import * +else: + import sys + + _file = globals()["__file__"] + sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__) diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pop2piano/configuration_pop2piano.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pop2piano/configuration_pop2piano.py new file mode 100644 index 0000000000000000000000000000000000000000..1b34c6384cac1c39100fdf6d458f751e76e4733b --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pop2piano/configuration_pop2piano.py @@ -0,0 +1,127 @@ +# Copyright 2023 The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""Pop2Piano model configuration""" + +from ...configuration_utils import PreTrainedConfig +from ...utils import logging + + +logger = logging.get_logger(__name__) + + +class Pop2PianoConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`Pop2PianoForConditionalGeneration`]. It is used + to instantiate a Pop2PianoForConditionalGeneration model according to the specified arguments, defining the model + architecture. Instantiating a configuration with the defaults will yield a similar configuration to that of the + Pop2Piano [sweetcocoa/pop2piano](https://huggingface.co/sweetcocoa/pop2piano) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Arguments: + vocab_size (`int`, *optional*, defaults to 2400): + Vocabulary size of the `Pop2PianoForConditionalGeneration` model. Defines the number of different tokens + that can be represented by the `inputs_ids` passed when calling [`Pop2PianoForConditionalGeneration`]. + composer_vocab_size (`int`, *optional*, defaults to 21): + Denotes the number of composers. + d_model (`int`, *optional*, defaults to 512): + Size of the encoder layers and the pooler layer. + d_kv (`int`, *optional*, defaults to 64): + Size of the key, query, value projections per attention head. The `inner_dim` of the projection layer will + be defined as `num_heads * d_kv`. + d_ff (`int`, *optional*, defaults to 2048): + Size of the intermediate feed forward layer in each `Pop2PianoBlock`. + num_layers (`int`, *optional*, defaults to 6): + Number of hidden layers in the Transformer encoder. + num_decoder_layers (`int`, *optional*): + Number of hidden layers in the Transformer decoder. Will use the same value as `num_layers` if not set. + num_heads (`int`, *optional*, defaults to 8): + Number of attention heads for each attention layer in the Transformer encoder. + relative_attention_num_buckets (`int`, *optional*, defaults to 32): + The number of buckets to use for each attention layer. + relative_attention_max_distance (`int`, *optional*, defaults to 128): + The maximum distance of the longer sequences for the bucket separation. + dropout_rate (`float`, *optional*, defaults to 0.1): + The ratio for all dropout layers. + layer_norm_epsilon (`float`, *optional*, defaults to 1e-6): + The epsilon used by the layer normalization layers. + initializer_factor (`float`, *optional*, defaults to 1.0): + A factor for initializing all weight matrices (should be kept to 1.0, used internally for initialization + testing). + feed_forward_proj (`string`, *optional*, defaults to `"gated-gelu"`): + Type of feed forward layer to be used. Should be one of `"relu"` or `"gated-gelu"`. + use_cache (`bool`, *optional*, defaults to `True`): + Whether or not the model should return the last key/values attentions (not used by all models). + dense_act_fn (`string`, *optional*, defaults to `"relu"`): + Type of Activation Function to be used in `Pop2PianoDenseActDense` and in `Pop2PianoDenseGatedActDense`. + """ + + model_type = "pop2piano" + keys_to_ignore_at_inference = ["past_key_values"] + + def __init__( + self, + vocab_size=2400, + composer_vocab_size=21, + d_model=512, + d_kv=64, + d_ff=2048, + num_layers=6, + num_decoder_layers=None, + num_heads=8, + relative_attention_num_buckets=32, + relative_attention_max_distance=128, + dropout_rate=0.1, + layer_norm_epsilon=1e-6, + initializer_factor=1.0, + feed_forward_proj="gated-gelu", + is_encoder_decoder=True, + use_cache=True, + pad_token_id=0, + eos_token_id=1, + dense_act_fn="relu", + is_decoder=False, + tie_word_embeddings=True, + **kwargs, + ): + self.is_decoder = is_decoder + self.tie_word_embeddings = tie_word_embeddings + self.vocab_size = vocab_size + self.composer_vocab_size = composer_vocab_size + self.d_model = d_model + self.d_kv = d_kv + self.d_ff = d_ff + self.num_layers = num_layers + self.num_decoder_layers = num_decoder_layers if num_decoder_layers is not None else self.num_layers + self.num_heads = num_heads + self.relative_attention_num_buckets = relative_attention_num_buckets + self.relative_attention_max_distance = relative_attention_max_distance + self.dropout_rate = dropout_rate + self.layer_norm_epsilon = layer_norm_epsilon + self.initializer_factor = initializer_factor + self.feed_forward_proj = feed_forward_proj + self.use_cache = use_cache + self.dense_act_fn = dense_act_fn + self.is_gated_act = self.feed_forward_proj.split("-")[0] == "gated" + self.hidden_size = self.d_model + self.num_attention_heads = num_heads + self.num_hidden_layers = num_layers + self.pad_token_id = pad_token_id + self.eos_token_id = eos_token_id + + super().__init__(is_encoder_decoder=is_encoder_decoder, **kwargs) + + +__all__ = ["Pop2PianoConfig"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pop2piano/feature_extraction_pop2piano.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pop2piano/feature_extraction_pop2piano.py new file mode 100644 index 0000000000000000000000000000000000000000..4e770fcb1b71f6471620cf6a4ae77861c6f51ff9 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pop2piano/feature_extraction_pop2piano.py @@ -0,0 +1,452 @@ +# Copyright 2023 The HuggingFace Inc. team. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""Feature extractor class for Pop2Piano""" + +import warnings + +import numpy +import numpy as np + +from ...audio_utils import mel_filter_bank, spectrogram +from ...feature_extraction_sequence_utils import SequenceFeatureExtractor +from ...feature_extraction_utils import BatchFeature +from ...utils import ( + TensorType, + is_essentia_available, + is_librosa_available, + is_scipy_available, + logging, + requires_backends, +) +from ...utils.import_utils import requires + + +if is_essentia_available(): + import essentia.standard + +if is_librosa_available(): + import librosa + +if is_scipy_available(): + import scipy + + +logger = logging.get_logger(__name__) + + +@requires(backends=("essentia", "librosa", "scipy", "torch")) +class Pop2PianoFeatureExtractor(SequenceFeatureExtractor): + r""" + Constructs a Pop2Piano feature extractor. + + This feature extractor inherits from [`~feature_extraction_sequence_utils.SequenceFeatureExtractor`] which contains + most of the main methods. Users should refer to this superclass for more information regarding those methods. + + This class extracts rhythm and preprocesses the audio before it is passed to the model. First the audio is passed + to `RhythmExtractor2013` algorithm which extracts the beat_times, beat positions and estimates their confidence as + well as tempo in bpm, then beat_times is interpolated and to get beatsteps. Later we calculate + extrapolated_beatsteps from it to be used in tokenizer. On the other hand audio is resampled to self.sampling_rate + and preprocessed and then log mel spectogram is computed from that to be used in our transformer model. + + Args: + sampling_rate (`int`, *optional*, defaults to 22050): + Target Sampling rate of audio signal. It's the sampling rate that we forward to the model. + padding_value (`int`, *optional*, defaults to 0): + Padding value used to pad the audio. Should correspond to silences. + window_size (`int`, *optional*, defaults to 4096): + Length of the window in samples to which the Fourier transform is applied. + hop_length (`int`, *optional*, defaults to 1024): + Step size between each window of the waveform, in samples. + min_frequency (`float`, *optional*, defaults to 10.0): + Lowest frequency that will be used in the log-mel spectrogram. + feature_size (`int`, *optional*, defaults to 512): + The feature dimension of the extracted features. + num_bars (`int`, *optional*, defaults to 2): + Determines interval between each sequence. + """ + + model_input_names = ["input_features", "beatsteps", "extrapolated_beatstep"] + + def __init__( + self, + sampling_rate: int = 22050, + padding_value: int = 0, + window_size: int = 4096, + hop_length: int = 1024, + min_frequency: float = 10.0, + feature_size: int = 512, + num_bars: int = 2, + **kwargs, + ): + super().__init__( + feature_size=feature_size, + sampling_rate=sampling_rate, + padding_value=padding_value, + **kwargs, + ) + self.sampling_rate = sampling_rate + self.padding_value = padding_value + self.window_size = window_size + self.hop_length = hop_length + self.min_frequency = min_frequency + self.feature_size = feature_size + self.num_bars = num_bars + self.mel_filters = mel_filter_bank( + num_frequency_bins=(self.window_size // 2) + 1, + num_mel_filters=self.feature_size, + min_frequency=self.min_frequency, + max_frequency=float(self.sampling_rate // 2), + sampling_rate=self.sampling_rate, + norm=None, + mel_scale="htk", + ) + + def mel_spectrogram(self, sequence: np.ndarray): + """ + Generates MelSpectrogram. + + Args: + sequence (`numpy.ndarray`): + The sequence of which the mel-spectrogram will be computed. + """ + mel_specs = [] + for seq in sequence: + window = np.hanning(self.window_size + 1)[:-1] + mel_specs.append( + spectrogram( + waveform=seq, + window=window, + frame_length=self.window_size, + hop_length=self.hop_length, + power=2.0, + mel_filters=self.mel_filters, + ) + ) + mel_specs = np.array(mel_specs) + + return mel_specs + + def extract_rhythm(self, audio: np.ndarray): + """ + This algorithm(`RhythmExtractor2013`) extracts the beat positions and estimates their confidence as well as + tempo in bpm for an audio signal. For more information please visit + https://essentia.upf.edu/reference/std_RhythmExtractor2013.html . + + Args: + audio(`numpy.ndarray`): + raw audio waveform which is passed to the Rhythm Extractor. + """ + requires_backends(self, ["essentia"]) + essentia_tracker = essentia.standard.RhythmExtractor2013(method="multifeature") + bpm, beat_times, confidence, estimates, essentia_beat_intervals = essentia_tracker(audio) + + return bpm, beat_times, confidence, estimates, essentia_beat_intervals + + def interpolate_beat_times( + self, beat_times: numpy.ndarray, steps_per_beat: numpy.ndarray, n_extend: numpy.ndarray + ): + """ + This method takes beat_times and then interpolates that using `scipy.interpolate.interp1d` and the output is + then used to convert raw audio to log-mel-spectrogram. + + Args: + beat_times (`numpy.ndarray`): + beat_times is passed into `scipy.interpolate.interp1d` for processing. + steps_per_beat (`int`): + used as an parameter to control the interpolation. + n_extend (`int`): + used as an parameter to control the interpolation. + """ + + requires_backends(self, ["scipy"]) + beat_times_function = scipy.interpolate.interp1d( + np.arange(beat_times.size), + beat_times, + bounds_error=False, + fill_value="extrapolate", + ) + + ext_beats = beat_times_function( + np.linspace(0, beat_times.size + n_extend - 1, beat_times.size * steps_per_beat + n_extend) + ) + + return ext_beats + + def preprocess_mel(self, audio: np.ndarray, beatstep: np.ndarray): + """ + Preprocessing for log-mel-spectrogram + + Args: + audio (`numpy.ndarray` of shape `(audio_length, )` ): + Raw audio waveform to be processed. + beatstep (`numpy.ndarray`): + Interpolated values of the raw audio. If beatstep[0] is greater than 0.0, then it will be shifted by + the value at beatstep[0]. + """ + + if audio is not None and len(audio.shape) != 1: + raise ValueError( + f"Expected `audio` to be a single channel audio input of shape `(n, )` but found shape {audio.shape}." + ) + if beatstep[0] > 0.0: + beatstep = beatstep - beatstep[0] + + num_steps = self.num_bars * 4 + num_target_steps = len(beatstep) + extrapolated_beatstep = self.interpolate_beat_times( + beat_times=beatstep, steps_per_beat=1, n_extend=(self.num_bars + 1) * 4 + 1 + ) + + sample_indices = [] + max_feature_length = 0 + for i in range(0, num_target_steps, num_steps): + start_idx = i + end_idx = min(i + num_steps, num_target_steps) + start_sample = int(extrapolated_beatstep[start_idx] * self.sampling_rate) + end_sample = int(extrapolated_beatstep[end_idx] * self.sampling_rate) + sample_indices.append((start_sample, end_sample)) + max_feature_length = max(max_feature_length, end_sample - start_sample) + padded_batch = [] + for start_sample, end_sample in sample_indices: + feature = audio[start_sample:end_sample] + padded_feature = np.pad( + feature, + ((0, max_feature_length - feature.shape[0]),), + "constant", + constant_values=0, + ) + padded_batch.append(padded_feature) + + padded_batch = np.asarray(padded_batch) + return padded_batch, extrapolated_beatstep + + def _pad(self, features: np.ndarray, add_zero_line=True): + features_shapes = [each_feature.shape for each_feature in features] + attention_masks, padded_features = [], [] + for i, each_feature in enumerate(features): + # To pad "input_features". + if len(each_feature.shape) == 3: + features_pad_value = max([*zip(*features_shapes)][1]) - features_shapes[i][1] + attention_mask = np.ones(features_shapes[i][:2], dtype=np.int64) + feature_padding = ((0, 0), (0, features_pad_value), (0, 0)) + attention_mask_padding = (feature_padding[0], feature_padding[1]) + + # To pad "beatsteps" and "extrapolated_beatstep". + else: + each_feature = each_feature.reshape(1, -1) + features_pad_value = max([*zip(*features_shapes)][0]) - features_shapes[i][0] + attention_mask = np.ones(features_shapes[i], dtype=np.int64).reshape(1, -1) + feature_padding = attention_mask_padding = ((0, 0), (0, features_pad_value)) + + each_padded_feature = np.pad(each_feature, feature_padding, "constant", constant_values=self.padding_value) + attention_mask = np.pad( + attention_mask, attention_mask_padding, "constant", constant_values=self.padding_value + ) + + if add_zero_line: + # if it is batched then we separate each examples using zero array + zero_array_len = max([*zip(*features_shapes)][1]) + + # we concatenate the zero array line here + each_padded_feature = np.concatenate( + [each_padded_feature, np.zeros([1, zero_array_len, self.feature_size])], axis=0 + ) + attention_mask = np.concatenate( + [attention_mask, np.zeros([1, zero_array_len], dtype=attention_mask.dtype)], axis=0 + ) + + padded_features.append(each_padded_feature) + attention_masks.append(attention_mask) + + padded_features = np.concatenate(padded_features, axis=0).astype(np.float32) + attention_masks = np.concatenate(attention_masks, axis=0).astype(np.int64) + + return padded_features, attention_masks + + def pad( + self, + inputs: BatchFeature, + is_batched: bool, + return_attention_mask: bool, + return_tensors: str | TensorType | None = None, + ): + """ + Pads the inputs to same length and returns attention_mask. + + Args: + inputs (`BatchFeature`): + Processed audio features. + is_batched (`bool`): + Whether inputs are batched or not. + return_attention_mask (`bool`): + Whether to return attention mask or not. + return_tensors (`str` or [`~utils.TensorType`], *optional*): + If set, will return tensors instead of list of python integers. Acceptable values are: + - `'pt'`: Return PyTorch `torch.Tensor` objects. + - `'np'`: Return Numpy `np.ndarray` objects. + If nothing is specified, it will return list of `np.ndarray` arrays. + Return: + `BatchFeature` with attention_mask, attention_mask_beatsteps and attention_mask_extrapolated_beatstep added + to it: + - **attention_mask** numpy.ndarray of shape `(batch_size, max_input_features_seq_length)` -- + Example : + 1, 1, 1, 0, 0 (audio 1, also here it is padded to max length of 5 that's why there are 2 zeros at + the end indicating they are padded) + + 0, 0, 0, 0, 0 (zero pad to separate audio 1 and 2) + + 1, 1, 1, 1, 1 (audio 2) + + 0, 0, 0, 0, 0 (zero pad to separate audio 2 and 3) + + 1, 1, 1, 1, 1 (audio 3) + - **attention_mask_beatsteps** numpy.ndarray of shape `(batch_size, max_beatsteps_seq_length)` + - **attention_mask_extrapolated_beatstep** numpy.ndarray of shape `(batch_size, + max_extrapolated_beatstep_seq_length)` + """ + + processed_features_dict = {} + for feature_name, feature_value in inputs.items(): + if feature_name == "input_features": + padded_feature_values, attention_mask = self._pad(feature_value, add_zero_line=True) + processed_features_dict[feature_name] = padded_feature_values + if return_attention_mask: + processed_features_dict["attention_mask"] = attention_mask + else: + padded_feature_values, attention_mask = self._pad(feature_value, add_zero_line=False) + processed_features_dict[feature_name] = padded_feature_values + if return_attention_mask: + processed_features_dict[f"attention_mask_{feature_name}"] = attention_mask + + # If we are processing only one example, we should remove the zero array line since we don't need it to + # separate examples from each other. + if not is_batched and not return_attention_mask: + processed_features_dict["input_features"] = processed_features_dict["input_features"][:-1, ...] + + outputs = BatchFeature(processed_features_dict, tensor_type=return_tensors) + + return outputs + + def __call__( + self, + audio: np.ndarray | list[float] | list[np.ndarray] | list[list[float]], + sampling_rate: int | list[int], + steps_per_beat: int = 2, + resample: bool | None = True, + return_attention_mask: bool | None = False, + return_tensors: str | TensorType | None = None, + **kwargs, + ) -> BatchFeature: + """ + Main method to featurize and prepare for the model. + + Args: + audio (`np.ndarray`, `List`): + The audio or batch of audio to be processed. Each audio can be a numpy array, a list of float values, a + list of numpy arrays or a list of list of float values. + sampling_rate (`int`): + The sampling rate at which the `audio` input was sampled. It is strongly recommended to pass + `sampling_rate` at the forward call to prevent silent errors. + steps_per_beat (`int`, *optional*, defaults to 2): + This is used in interpolating `beat_times`. + resample (`bool`, *optional*, defaults to `True`): + Determines whether to resample the audio to `sampling_rate` or not before processing. Must be True + during inference. + return_attention_mask (`bool` *optional*, defaults to `False`): + Denotes if attention_mask for input_features, beatsteps and extrapolated_beatstep will be given as + output or not. Automatically set to True for batched inputs. + return_tensors (`str` or [`~utils.TensorType`], *optional*): + If set, will return tensors instead of list of python integers. Acceptable values are: + - `'pt'`: Return PyTorch `torch.Tensor` objects. + - `'np'`: Return Numpy `np.ndarray` objects. + If nothing is specified, it will return list of `np.ndarray` arrays. + """ + + requires_backends(self, ["librosa"]) + is_batched = isinstance(audio, (list, tuple)) and isinstance(audio[0], (np.ndarray, tuple, list)) + if is_batched: + # This enables the user to process files of different sampling_rate at same time + if not isinstance(sampling_rate, list): + raise ValueError( + "Please give sampling_rate of each audio separately when you are passing multiple raw_audios at the same time. " + f"Received {sampling_rate}, expected [audio_1_sr, ..., audio_n_sr]." + ) + return_attention_mask = True if return_attention_mask is None else return_attention_mask + else: + audio = [audio] + sampling_rate = [sampling_rate] + return_attention_mask = False if return_attention_mask is None else return_attention_mask + + batch_input_features, batch_beatsteps, batch_ext_beatstep = [], [], [] + for single_raw_audio, single_sampling_rate in zip(audio, sampling_rate): + bpm, beat_times, confidence, estimates, essentia_beat_intervals = self.extract_rhythm( + audio=single_raw_audio + ) + beatsteps = self.interpolate_beat_times(beat_times=beat_times, steps_per_beat=steps_per_beat, n_extend=1) + + if self.sampling_rate != single_sampling_rate and self.sampling_rate is not None: + if resample: + # Change sampling_rate to self.sampling_rate + single_raw_audio = librosa.core.resample( + single_raw_audio, + orig_sr=single_sampling_rate, + target_sr=self.sampling_rate, + res_type="kaiser_best", + ) + else: + warnings.warn( + f"The sampling_rate of the provided audio is different from the target sampling_rate " + f"of the Feature Extractor, {self.sampling_rate} vs {single_sampling_rate}. " + f"In these cases it is recommended to use `resample=True` in the `__call__` method to " + f"get the optimal behaviour." + ) + + single_sampling_rate = self.sampling_rate + start_sample = int(beatsteps[0] * single_sampling_rate) + end_sample = int(beatsteps[-1] * single_sampling_rate) + + input_features, extrapolated_beatstep = self.preprocess_mel( + single_raw_audio[start_sample:end_sample], beatsteps - beatsteps[0] + ) + + mel_specs = self.mel_spectrogram(input_features.astype(np.float32)) + + # apply np.log to get log mel-spectrograms + log_mel_specs = np.log(np.clip(mel_specs, a_min=1e-6, a_max=None)) + + input_features = np.transpose(log_mel_specs, (0, -1, -2)) + + batch_input_features.append(input_features) + batch_beatsteps.append(beatsteps) + batch_ext_beatstep.append(extrapolated_beatstep) + + output = BatchFeature( + { + "input_features": batch_input_features, + "beatsteps": batch_beatsteps, + "extrapolated_beatstep": batch_ext_beatstep, + } + ) + + output = self.pad( + output, + is_batched=is_batched, + return_attention_mask=return_attention_mask, + return_tensors=return_tensors, + ) + + return output + + +__all__ = ["Pop2PianoFeatureExtractor"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pop2piano/modeling_pop2piano.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pop2piano/modeling_pop2piano.py new file mode 100644 index 0000000000000000000000000000000000000000..4a3f8d402dd1c106b8e20873f0f324b3ab9dd573 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pop2piano/modeling_pop2piano.py @@ -0,0 +1,1112 @@ +# Copyright 2023 The Pop2Piano Authors and The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""PyTorch Pop2Piano model.""" + +import copy +import math + +import torch +from torch import nn +from torch.nn import CrossEntropyLoss + +from transformers.generation import GenerationConfig + +from ... import initialization as init +from ...activations import ACT2FN +from ...cache_utils import Cache, DynamicCache, EncoderDecoderCache +from ...generation import GenerationMixin +from ...masking_utils import create_causal_mask +from ...modeling_layers import GradientCheckpointingLayer +from ...modeling_outputs import BaseModelOutput, BaseModelOutputWithPastAndCrossAttentions, Seq2SeqLMOutput +from ...modeling_utils import PreTrainedModel +from ...utils import auto_docstring, is_torchdynamo_compiling, logging +from .configuration_pop2piano import Pop2PianoConfig + + +logger = logging.get_logger(__name__) + +_load_pop2piano_layer_norm = True + +try: + from apex.normalization import FusedRMSNorm + + _load_pop2piano_layer_norm = False + + logger.info("Discovered apex.normalization.FusedRMSNorm - will use it instead of Pop2PianoLayerNorm") +except ImportError: + # using the normal Pop2PianoLayerNorm + pass +except Exception: + logger.warning("Discovered apex but it failed to load, falling back to Pop2PianoLayerNorm") + + +# Copied from transformers.models.t5.modeling_t5.T5LayerNorm with T5->Pop2Piano +class Pop2PianoLayerNorm(nn.Module): + def __init__(self, hidden_size, eps=1e-6): + """ + Construct a layernorm module in the Pop2Piano style. No bias and no subtraction of mean. + """ + super().__init__() + self.weight = nn.Parameter(torch.ones(hidden_size)) + self.variance_epsilon = eps + + def forward(self, hidden_states): + # Pop2Piano uses a layer_norm which only scales and doesn't shift, which is also known as Root Mean + # Square Layer Normalization https://huggingface.co/papers/1910.07467 thus variance is calculated + # w/o mean and there is no bias. Additionally we want to make sure that the accumulation for + # half-precision inputs is done in fp32 + + variance = hidden_states.to(torch.float32).pow(2).mean(-1, keepdim=True) + hidden_states = hidden_states * torch.rsqrt(variance + self.variance_epsilon) + + # convert into half-precision if necessary + if self.weight.dtype in [torch.float16, torch.bfloat16]: + hidden_states = hidden_states.to(self.weight.dtype) + + return self.weight * hidden_states + + +if not _load_pop2piano_layer_norm: + Pop2PianoLayerNorm = FusedRMSNorm + + +# Copied from transformers.models.t5.modeling_t5.T5DenseActDense with T5->Pop2Piano,t5->pop2piano +class Pop2PianoDenseActDense(nn.Module): + def __init__(self, config: Pop2PianoConfig): + super().__init__() + self.wi = nn.Linear(config.d_model, config.d_ff, bias=False) + self.wo = nn.Linear(config.d_ff, config.d_model, bias=False) + self.dropout = nn.Dropout(config.dropout_rate) + self.act = ACT2FN[config.dense_act_fn] + + def forward(self, hidden_states): + hidden_states = self.wi(hidden_states) + hidden_states = self.act(hidden_states) + hidden_states = self.dropout(hidden_states) + if ( + isinstance(self.wo.weight, torch.Tensor) + and hidden_states.dtype != self.wo.weight.dtype + and self.wo.weight.dtype != torch.int8 + ): + hidden_states = hidden_states.to(self.wo.weight.dtype) + hidden_states = self.wo(hidden_states) + return hidden_states + + +# Copied from transformers.models.t5.modeling_t5.T5DenseGatedActDense with T5->Pop2Piano +class Pop2PianoDenseGatedActDense(nn.Module): + def __init__(self, config: Pop2PianoConfig): + super().__init__() + self.wi_0 = nn.Linear(config.d_model, config.d_ff, bias=False) + self.wi_1 = nn.Linear(config.d_model, config.d_ff, bias=False) + self.wo = nn.Linear(config.d_ff, config.d_model, bias=False) + self.dropout = nn.Dropout(config.dropout_rate) + self.act = ACT2FN[config.dense_act_fn] + + def forward(self, hidden_states): + hidden_gelu = self.act(self.wi_0(hidden_states)) + hidden_linear = self.wi_1(hidden_states) + hidden_states = hidden_gelu * hidden_linear + hidden_states = self.dropout(hidden_states) + + # To make 8bit quantization work for google/flan-t5-xxl, self.wo is kept in float32. + # See https://github.com/huggingface/transformers/issues/20287 + # we also make sure the weights are not in `int8` in case users will force `_keep_in_fp32_modules` to be `None`` + if ( + isinstance(self.wo.weight, torch.Tensor) + and hidden_states.dtype != self.wo.weight.dtype + and self.wo.weight.dtype != torch.int8 + ): + hidden_states = hidden_states.to(self.wo.weight.dtype) + + hidden_states = self.wo(hidden_states) + return hidden_states + + +# Copied from transformers.models.t5.modeling_t5.T5LayerFF with T5->Pop2Piano +class Pop2PianoLayerFF(nn.Module): + def __init__(self, config: Pop2PianoConfig): + super().__init__() + if config.is_gated_act: + self.DenseReluDense = Pop2PianoDenseGatedActDense(config) + else: + self.DenseReluDense = Pop2PianoDenseActDense(config) + + self.layer_norm = Pop2PianoLayerNorm(config.d_model, eps=config.layer_norm_epsilon) + self.dropout = nn.Dropout(config.dropout_rate) + + def forward(self, hidden_states): + forwarded_states = self.layer_norm(hidden_states) + forwarded_states = self.DenseReluDense(forwarded_states) + hidden_states = hidden_states + self.dropout(forwarded_states) + return hidden_states + + +# Copied from transformers.models.t5.modeling_t5.T5Attention with T5->Pop2Piano,t5->pop2piano +class Pop2PianoAttention(nn.Module): + def __init__( + self, + config: Pop2PianoConfig, + has_relative_attention_bias=False, + layer_idx: int | None = None, + ): + super().__init__() + self.is_decoder = config.is_decoder + self.has_relative_attention_bias = has_relative_attention_bias + self.relative_attention_num_buckets = config.relative_attention_num_buckets + self.relative_attention_max_distance = config.relative_attention_max_distance + self.d_model = config.d_model + self.key_value_proj_dim = config.d_kv + self.n_heads = config.num_heads + self.dropout = config.dropout_rate + self.inner_dim = self.n_heads * self.key_value_proj_dim + self.layer_idx = layer_idx + if layer_idx is None and self.is_decoder: + logger.warning_once( + f"Instantiating a decoder {self.__class__.__name__} without passing `layer_idx` is not recommended and " + "will to errors during the forward call, if caching is used. Please make sure to provide a `layer_idx` " + "when creating this class." + ) + + self.q = nn.Linear(self.d_model, self.inner_dim, bias=False) + self.k = nn.Linear(self.d_model, self.inner_dim, bias=False) + self.v = nn.Linear(self.d_model, self.inner_dim, bias=False) + self.o = nn.Linear(self.inner_dim, self.d_model, bias=False) + + if self.has_relative_attention_bias: + self.relative_attention_bias = nn.Embedding(self.relative_attention_num_buckets, self.n_heads) + + self.gradient_checkpointing = False + + @staticmethod + def _relative_position_bucket(relative_position, bidirectional=True, num_buckets=32, max_distance=128): + """ + Adapted from Mesh Tensorflow: + https://github.com/tensorflow/mesh/blob/0cb87fe07da627bf0b7e60475d59f95ed6b5be3d/mesh_tensorflow/transformer/transformer_layers.py#L593 + + Translate relative position to a bucket number for relative attention. The relative position is defined as + memory_position - query_position, i.e. the distance in tokens from the attending position to the attended-to + position. If bidirectional=False, then positive relative positions are invalid. We use smaller buckets for + small absolute relative_position and larger buckets for larger absolute relative_positions. All relative + positions >=max_distance map to the same bucket. All relative positions <=-max_distance map to the same bucket. + This should allow for more graceful generalization to longer sequences than the model has been trained on + + Args: + relative_position: an int32 Tensor + bidirectional: a boolean - whether the attention is bidirectional + num_buckets: an integer + max_distance: an integer + + Returns: + a Tensor with the same shape as relative_position, containing int32 values in the range [0, num_buckets) + """ + relative_buckets = 0 + if bidirectional: + num_buckets //= 2 + relative_buckets += (relative_position > 0).to(torch.long) * num_buckets + relative_position = torch.abs(relative_position) + else: + relative_position = -torch.min(relative_position, torch.zeros_like(relative_position)) + # now relative_position is in the range [0, inf) + + # half of the buckets are for exact increments in positions + max_exact = num_buckets // 2 + is_small = relative_position < max_exact + + # The other half of the buckets are for logarithmically bigger bins in positions up to max_distance + relative_position_if_large = max_exact + ( + torch.log(relative_position.float() / max_exact) + / math.log(max_distance / max_exact) + * (num_buckets - max_exact) + ).to(torch.long) + relative_position_if_large = torch.min( + relative_position_if_large, torch.full_like(relative_position_if_large, num_buckets - 1) + ) + + relative_buckets += torch.where(is_small, relative_position, relative_position_if_large) + return relative_buckets + + def compute_bias(self, query_length, key_length, device=None, cache_position=None): + """Compute binned relative position bias""" + if device is None: + device = self.relative_attention_bias.weight.device + if cache_position is None: + context_position = torch.arange(query_length, dtype=torch.long, device=device)[:, None] + else: + context_position = cache_position[:, None].to(device) + memory_position = torch.arange(key_length, dtype=torch.long, device=device)[None, :] + relative_position = memory_position - context_position # shape (query_length, key_length) + relative_position_bucket = self._relative_position_bucket( + relative_position, # shape (query_length, key_length) + bidirectional=(not self.is_decoder), + num_buckets=self.relative_attention_num_buckets, + max_distance=self.relative_attention_max_distance, + ) + values = self.relative_attention_bias(relative_position_bucket) # shape (query_length, key_length, num_heads) + values = values.permute([2, 0, 1]).unsqueeze(0) # shape (1, num_heads, query_length, key_length) + return values + + def forward( + self, + hidden_states, + mask=None, + key_value_states=None, + position_bias=None, + past_key_values=None, + query_length=None, + use_cache=False, + output_attentions=False, + cache_position=None, + ): + """ + Self-attention (if key_value_states is None) or attention over source sentence (provided by key_value_states). + """ + # Input is (batch_size, seq_length, dim) + # Mask is (batch_size, 1, 1, key_length) (non-causal encoder) or (batch_size, 1, seq_length, key_length) (causal decoder) + batch_size, seq_length = hidden_states.shape[:2] + + # if key_value_states are provided this layer is used as a cross-attention layer for the decoder + is_cross_attention = key_value_states is not None + + query_states = self.q(hidden_states) + query_states = query_states.view(batch_size, -1, self.n_heads, self.key_value_proj_dim).transpose(1, 2) + + # Check is encoder-decoder model is being used. Otherwise we'll get `DynamicCache` + is_updated = False + if isinstance(past_key_values, EncoderDecoderCache): + is_updated = past_key_values.is_updated.get(self.layer_idx) + if is_cross_attention: + # after the first generated id, we can subsequently re-use all key/value_states from cache + curr_past_key_values = past_key_values.cross_attention_cache + else: + curr_past_key_values = past_key_values.self_attention_cache + else: + curr_past_key_values = past_key_values + + current_states = key_value_states if is_cross_attention else hidden_states + if is_cross_attention and past_key_values is not None and is_updated: + # reuse k,v, cross_attentions + key_states = curr_past_key_values.layers[self.layer_idx].keys + value_states = curr_past_key_values.layers[self.layer_idx].values + else: + key_states = self.k(current_states) + value_states = self.v(current_states) + key_states = key_states.view(batch_size, -1, self.n_heads, self.key_value_proj_dim).transpose(1, 2) + value_states = value_states.view(batch_size, -1, self.n_heads, self.key_value_proj_dim).transpose(1, 2) + + if past_key_values is not None: + # save all key/value_states to cache to be re-used for fast auto-regressive generation + cache_position = cache_position if not is_cross_attention else None + key_states, value_states = curr_past_key_values.update( + key_states, value_states, self.layer_idx, {"cache_position": cache_position} + ) + # set flag that curr layer for cross-attn is already updated so we can re-use in subsequent calls + if is_cross_attention and isinstance(past_key_values, EncoderDecoderCache): + past_key_values.is_updated[self.layer_idx] = True + + # compute scores, equivalent of torch.einsum("bnqd,bnkd->bnqk", query_states, key_states), compatible with onnx op>9 + scores = torch.matmul(query_states, key_states.transpose(3, 2)) + + if position_bias is None: + key_length = key_states.shape[-2] + # cache position is 0-indexed so we add 1 to get the real length of queries (aka with past) + real_seq_length = query_length if query_length is not None else cache_position[-1] + 1 + if not self.has_relative_attention_bias: + position_bias = torch.zeros( + (1, self.n_heads, seq_length, key_length), device=scores.device, dtype=scores.dtype + ) + if self.gradient_checkpointing and self.training: + position_bias.requires_grad = True + else: + position_bias = self.compute_bias( + real_seq_length, key_length, device=scores.device, cache_position=cache_position + ) + position_bias = position_bias[:, :, -seq_length:, :] + + if mask is not None: + causal_mask = mask[:, :, :, : key_states.shape[-2]] + position_bias = position_bias + causal_mask + + position_bias_masked = position_bias + scores += position_bias_masked + + # (batch_size, n_heads, seq_length, key_length) + attn_weights = nn.functional.softmax(scores.float(), dim=-1).type_as(scores) + attn_weights = nn.functional.dropout(attn_weights, p=self.dropout, training=self.training) + + attn_output = torch.matmul(attn_weights, value_states) + + attn_output = attn_output.transpose(1, 2).contiguous() + attn_output = attn_output.view(batch_size, -1, self.inner_dim) + attn_output = self.o(attn_output) + + outputs = (attn_output, position_bias) + + if output_attentions: + outputs = outputs + (attn_weights,) + return outputs + + +# Copied from transformers.models.t5.modeling_t5.T5LayerSelfAttention with T5->Pop2Piano,t5->pop2piano +class Pop2PianoLayerSelfAttention(nn.Module): + def __init__(self, config, has_relative_attention_bias=False, layer_idx: int | None = None): + super().__init__() + self.SelfAttention = Pop2PianoAttention( + config, has_relative_attention_bias=has_relative_attention_bias, layer_idx=layer_idx + ) + self.layer_norm = Pop2PianoLayerNorm(config.d_model, eps=config.layer_norm_epsilon) + self.dropout = nn.Dropout(config.dropout_rate) + + def forward( + self, + hidden_states, + attention_mask=None, + position_bias=None, + past_key_values=None, + use_cache=False, + output_attentions=False, + cache_position=None, + ): + normed_hidden_states = self.layer_norm(hidden_states) + attention_output = self.SelfAttention( + normed_hidden_states, + mask=attention_mask, + position_bias=position_bias, + past_key_values=past_key_values, + use_cache=use_cache, + output_attentions=output_attentions, + cache_position=cache_position, + ) + hidden_states = hidden_states + self.dropout(attention_output[0]) + outputs = (hidden_states,) + attention_output[1:] # add attentions if we output them + return outputs + + +# Copied from transformers.models.t5.modeling_t5.T5LayerCrossAttention with T5->Pop2Piano,t5->pop2piano +class Pop2PianoLayerCrossAttention(nn.Module): + def __init__(self, config, layer_idx: int | None = None): + super().__init__() + self.EncDecAttention = Pop2PianoAttention(config, has_relative_attention_bias=False, layer_idx=layer_idx) + self.layer_norm = Pop2PianoLayerNorm(config.d_model, eps=config.layer_norm_epsilon) + self.dropout = nn.Dropout(config.dropout_rate) + + def forward( + self, + hidden_states, + key_value_states, + attention_mask=None, + position_bias=None, + past_key_values=None, + use_cache=False, + query_length=None, + output_attentions=False, + cache_position=None, + ): + normed_hidden_states = self.layer_norm(hidden_states) + attention_output = self.EncDecAttention( + normed_hidden_states, + mask=attention_mask, + key_value_states=key_value_states, + position_bias=position_bias, + past_key_values=past_key_values, + use_cache=use_cache, + query_length=query_length, + output_attentions=output_attentions, + cache_position=cache_position, + ) + layer_output = hidden_states + self.dropout(attention_output[0]) + outputs = (layer_output,) + attention_output[1:] # add attentions if we output them + return outputs + + +# Copied from transformers.models.t5.modeling_t5.T5Block with T5->Pop2Piano,t5->pop2piano +class Pop2PianoBlock(GradientCheckpointingLayer): + def __init__(self, config, has_relative_attention_bias=False, layer_idx: int | None = None): + super().__init__() + self.is_decoder = config.is_decoder + self.layer = nn.ModuleList() + self.layer.append( + Pop2PianoLayerSelfAttention( + config, has_relative_attention_bias=has_relative_attention_bias, layer_idx=layer_idx + ) + ) + if self.is_decoder: + self.layer.append(Pop2PianoLayerCrossAttention(config, layer_idx=layer_idx)) + + self.layer.append(Pop2PianoLayerFF(config)) + + def forward( + self, + hidden_states, + attention_mask=None, + position_bias=None, + encoder_hidden_states=None, + encoder_attention_mask=None, + encoder_decoder_position_bias=None, + past_key_values=None, + use_cache=False, + output_attentions=False, + return_dict=True, + cache_position=None, + ): + self_attention_outputs = self.layer[0]( + hidden_states, + attention_mask=attention_mask, + position_bias=position_bias, + past_key_values=past_key_values, + use_cache=use_cache, + output_attentions=output_attentions, + cache_position=cache_position, + ) + hidden_states = self_attention_outputs[0] + attention_outputs = self_attention_outputs[1:] # Keep self-attention outputs and relative position weights + + # clamp inf values to enable fp16 training + if hidden_states.dtype == torch.float16: + clamp_value = torch.where( + torch.isinf(hidden_states).any(), + torch.finfo(hidden_states.dtype).max - 1000, + torch.finfo(hidden_states.dtype).max, + ) + hidden_states = torch.clamp(hidden_states, min=-clamp_value, max=clamp_value) + + do_cross_attention = self.is_decoder and encoder_hidden_states is not None + if do_cross_attention: + cross_attention_outputs = self.layer[1]( + hidden_states, + key_value_states=encoder_hidden_states, + attention_mask=encoder_attention_mask, + position_bias=encoder_decoder_position_bias, + past_key_values=past_key_values, + query_length=cache_position[-1] + 1, + use_cache=use_cache, + output_attentions=output_attentions, + ) + hidden_states = cross_attention_outputs[0] + + # clamp inf values to enable fp16 training + if hidden_states.dtype == torch.float16: + clamp_value = torch.where( + torch.isinf(hidden_states).any(), + torch.finfo(hidden_states.dtype).max - 1000, + torch.finfo(hidden_states.dtype).max, + ) + hidden_states = torch.clamp(hidden_states, min=-clamp_value, max=clamp_value) + + # Keep cross-attention outputs and relative position weights + attention_outputs = attention_outputs + cross_attention_outputs[1:] + + # Apply Feed Forward layer + hidden_states = self.layer[-1](hidden_states) + + # clamp inf values to enable fp16 training + if hidden_states.dtype == torch.float16: + clamp_value = torch.where( + torch.isinf(hidden_states).any(), + torch.finfo(hidden_states.dtype).max - 1000, + torch.finfo(hidden_states.dtype).max, + ) + hidden_states = torch.clamp(hidden_states, min=-clamp_value, max=clamp_value) + + outputs = (hidden_states,) + + return ( + outputs + attention_outputs + ) # hidden-states, (self-attention position bias), (self-attention weights), (cross-attention position bias), (cross-attention weights) + + +@auto_docstring +class Pop2PianoPreTrainedModel(PreTrainedModel): + config: Pop2PianoConfig + base_model_prefix = "transformer" + output_modalities = ("audio",) + supports_gradient_checkpointing = True + + _can_compile_fullgraph = False + _no_split_modules = ["Pop2PianoBlock"] + _keep_in_fp32_modules = ["wo"] + + @torch.no_grad() + def _init_weights(self, module): + """Initialize the weights""" + factor = self.config.initializer_factor # Used for testing weights initialization + if isinstance(module, Pop2PianoLayerNorm): + init.constant_(module.weight, factor * 1.0) + elif isinstance(module, Pop2PianoConcatEmbeddingToMel): + init.normal_(module.embedding.weight, mean=0.0, std=factor * 1.0) + elif isinstance(module, Pop2PianoForConditionalGeneration): + init.normal_(module.shared.weight, mean=0.0, std=factor * 1.0) + if hasattr(module, "lm_head"): + init.normal_(module.lm_head.weight, mean=0.0, std=factor * 1.0) + elif isinstance(module, Pop2PianoDenseActDense): + init.normal_(module.wi.weight, mean=0.0, std=factor * ((self.config.d_model) ** -0.5)) + if hasattr(module.wi, "bias") and module.wi.bias is not None: + init.zeros_(module.wi.bias) + init.normal_(module.wo.weight, mean=0.0, std=factor * ((self.config.d_ff) ** -0.5)) + if hasattr(module.wo, "bias") and module.wo.bias is not None: + init.zeros_(module.wo.bias) + elif isinstance(module, Pop2PianoDenseGatedActDense): + init.normal_(module.wi_0.weight, mean=0.0, std=factor * ((self.config.d_model) ** -0.5)) + if hasattr(module.wi_0, "bias") and module.wi_0.bias is not None: + init.zeros_(module.wi_0.bias) + init.normal_(module.wi_1.weight, mean=0.0, std=factor * ((self.config.d_model) ** -0.5)) + if hasattr(module.wi_1, "bias") and module.wi_1.bias is not None: + init.zeros_(module.wi_1.bias) + init.normal_(module.wo.weight, mean=0.0, std=factor * ((self.config.d_ff) ** -0.5)) + if hasattr(module.wo, "bias") and module.wo.bias is not None: + init.zeros_(module.wo.bias) + elif isinstance(module, Pop2PianoAttention): + d_model = self.config.d_model + key_value_proj_dim = self.config.d_kv + n_heads = self.config.num_heads + init.normal_(module.q.weight, mean=0.0, std=factor * ((d_model * key_value_proj_dim) ** -0.5)) + init.normal_(module.k.weight, mean=0.0, std=factor * (d_model**-0.5)) + init.normal_(module.v.weight, mean=0.0, std=factor * (d_model**-0.5)) + init.normal_(module.o.weight, mean=0.0, std=factor * ((n_heads * key_value_proj_dim) ** -0.5)) + if module.has_relative_attention_bias: + init.normal_(module.relative_attention_bias.weight, mean=0.0, std=factor * ((d_model) ** -0.5)) + + def _shift_right(self, input_ids): + decoder_start_token_id = self.config.decoder_start_token_id + pad_token_id = self.config.pad_token_id + + if decoder_start_token_id is None: + raise ValueError( + "self.model.config.decoder_start_token_id has to be defined. In Pop2Piano it is usually set to the pad_token_id." + ) + + shifted_input_ids = input_ids.new_zeros(input_ids.shape) + shifted_input_ids[..., 1:] = input_ids[..., :-1].clone() + shifted_input_ids[..., 0] = decoder_start_token_id + + if pad_token_id is None: + raise ValueError("self.model.config.pad_token_id has to be defined.") + # replace possible -100 values in labels by `pad_token_id` + shifted_input_ids.masked_fill_(shifted_input_ids == -100, pad_token_id) + + return shifted_input_ids + + +class Pop2PianoStack(Pop2PianoPreTrainedModel): + # Copied from transformers.models.t5.modeling_t5.T5Stack.__init__ with T5->Pop2Piano,t5->pop2piano + def __init__(self, config): + super().__init__(config) + + self.embed_tokens = nn.Embedding(config.vocab_size, config.d_model) + self.is_decoder = config.is_decoder + + self.block = nn.ModuleList( + [ + Pop2PianoBlock(config, has_relative_attention_bias=bool(i == 0), layer_idx=i) + for i in range(config.num_layers) + ] + ) + self.final_layer_norm = Pop2PianoLayerNorm(config.d_model, eps=config.layer_norm_epsilon) + self.dropout = nn.Dropout(config.dropout_rate) + + # Initialize weights and apply final processing + self.post_init() + self.gradient_checkpointing = False + + # Copied from transformers.models.t5.modeling_t5.T5Stack.set_input_embeddings + def set_input_embeddings(self, new_embeddings): + self.embed_tokens = new_embeddings + + def forward( + self, + input_ids=None, + attention_mask=None, + encoder_hidden_states=None, + encoder_attention_mask=None, + inputs_embeds=None, + past_key_values=None, + use_cache=None, + output_attentions=None, + output_hidden_states=None, + return_dict=None, + cache_position=None, + **kwargs, + ): + use_cache = use_cache if use_cache is not None else self.config.use_cache + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + if input_ids is not None and inputs_embeds is not None: + err_msg_prefix = "decoder_" if self.is_decoder else "" + raise ValueError( + f"You cannot specify both {err_msg_prefix}input_ids and {err_msg_prefix}inputs_embeds at the same time" + ) + elif input_ids is not None: + input_shape = input_ids.size() + input_ids = input_ids.view(-1, input_shape[-1]) + elif inputs_embeds is not None: + input_shape = inputs_embeds.size()[:-1] + else: + err_msg_prefix = "decoder_" if self.is_decoder else "" + raise ValueError(f"You have to specify either {err_msg_prefix}input_ids or {err_msg_prefix}inputs_embeds") + + if self.gradient_checkpointing and self.training: + if use_cache: + logger.warning_once( + "`use_cache=True` is incompatible with gradient checkpointing. Setting `use_cache=False`..." + ) + use_cache = False + + if inputs_embeds is None: + if self.embed_tokens is None: + raise ValueError("You have to initialize the model with valid token embeddings") + inputs_embeds = self.embed_tokens(input_ids) + + batch_size, seq_length = input_shape + + if use_cache is True: + if not self.is_decoder: + raise ValueError(f"`use_cache` can only be set to `True` if {self} is used as a decoder") + + if self.is_decoder: + if use_cache and past_key_values is None: + if self.config.is_encoder_decoder: + past_key_values = EncoderDecoderCache( + DynamicCache(config=self.config), DynamicCache(config=self.config) + ) + else: + past_key_values = DynamicCache(config=self.config) + elif not self.is_decoder: + # do not pass cache object down the line for encoder stack + # it messes indexing later in decoder-stack because cache object is modified in-place + past_key_values = None + + past_key_values_length = past_key_values.get_seq_length() if past_key_values is not None else 0 + if cache_position is None: + cache_position = torch.arange( + past_key_values_length, past_key_values_length + seq_length, device=inputs_embeds.device + ) + + if attention_mask is None and not is_torchdynamo_compiling(): + # required mask seq length can be calculated via length of past cache + mask_seq_length = past_key_values_length + seq_length + attention_mask = torch.ones(batch_size, mask_seq_length, device=inputs_embeds.device) + + if self.config.is_decoder: + causal_mask = create_causal_mask( + config=self.config, + inputs_embeds=inputs_embeds, + attention_mask=attention_mask, + cache_position=cache_position, + past_key_values=past_key_values, + ) + else: + causal_mask = attention_mask[:, None, None, :] + causal_mask = causal_mask.to(dtype=inputs_embeds.dtype) + causal_mask = (1.0 - causal_mask) * torch.finfo(inputs_embeds.dtype).min + + # If a 2D or 3D attention mask is provided for the cross-attention + # we need to make broadcastable to [batch_size, num_heads, seq_length, seq_length] + if self.is_decoder and encoder_hidden_states is not None: + encoder_batch_size, encoder_sequence_length, _ = encoder_hidden_states.size() + encoder_hidden_shape = (encoder_batch_size, encoder_sequence_length) + if encoder_attention_mask is None: + encoder_attention_mask = torch.ones(encoder_hidden_shape, device=inputs_embeds.device) + encoder_extended_attention_mask = self.invert_attention_mask(encoder_attention_mask) + else: + encoder_extended_attention_mask = None + + all_hidden_states = () if output_hidden_states else None + all_attentions = () if output_attentions else None + all_cross_attentions = () if (output_attentions and self.is_decoder) else None + position_bias = None + encoder_decoder_position_bias = None + + hidden_states = self.dropout(inputs_embeds) + + for i, layer_module in enumerate(self.block): + if output_hidden_states: + all_hidden_states = all_hidden_states + (hidden_states,) + + layer_outputs = layer_module( + hidden_states, + causal_mask, + position_bias, + encoder_hidden_states, + encoder_extended_attention_mask, + encoder_decoder_position_bias, # as a positional argument for gradient checkpointing + past_key_values=past_key_values, + use_cache=use_cache, + output_attentions=output_attentions, + cache_position=cache_position, + ) + + hidden_states = layer_outputs[0] + + # We share the position biases between the layers - the first layer store them + # layer_outputs = hidden-states, key-value-states (self-attention position bias), (self-attention weights), + # (cross-attention position bias), (cross-attention weights) + position_bias = layer_outputs[1] + if self.is_decoder and encoder_hidden_states is not None: + encoder_decoder_position_bias = layer_outputs[3 if output_attentions else 2] + + if output_attentions: + all_attentions = all_attentions + (layer_outputs[2],) + if self.is_decoder: + all_cross_attentions = all_cross_attentions + (layer_outputs[4],) + + hidden_states = self.final_layer_norm(hidden_states) + hidden_states = self.dropout(hidden_states) + + # Add last layer + if output_hidden_states: + all_hidden_states = all_hidden_states + (hidden_states,) + + if not return_dict: + return tuple( + v + for v in [ + hidden_states, + past_key_values, + all_hidden_states, + all_attentions, + all_cross_attentions, + ] + if v is not None + ) + return BaseModelOutputWithPastAndCrossAttentions( + last_hidden_state=hidden_states, + past_key_values=past_key_values, + hidden_states=all_hidden_states, + attentions=all_attentions, + cross_attentions=all_cross_attentions, + ) + + +class Pop2PianoConcatEmbeddingToMel(nn.Module): + """Embedding Matrix for `composer` tokens.""" + + def __init__(self, config): + super().__init__() + self.embedding = nn.Embedding(num_embeddings=config.composer_vocab_size, embedding_dim=config.d_model) + + def forward(self, feature, index_value, embedding_offset): + index_shifted = index_value - embedding_offset + composer_embedding = self.embedding(index_shifted).unsqueeze(1) + inputs_embeds = torch.cat([composer_embedding, feature], dim=1) + return inputs_embeds + + +@auto_docstring( + custom_intro=""" + Pop2Piano Model with a `language modeling` head on top. + """ +) +class Pop2PianoForConditionalGeneration(Pop2PianoPreTrainedModel, GenerationMixin): + _tied_weights_keys = { + "encoder.embed_tokens.weight": "shared.weight", + "decoder.embed_tokens.weight": "shared.weight", + } + + def __init__(self, config: Pop2PianoConfig): + super().__init__(config) + self.config = config + self.model_dim = config.d_model + + self.shared = nn.Embedding(config.vocab_size, config.d_model) + + self.mel_conditioner = Pop2PianoConcatEmbeddingToMel(config) + + encoder_config = copy.deepcopy(config) + encoder_config.is_decoder = False + encoder_config.use_cache = False + + self.encoder = Pop2PianoStack(encoder_config) + + decoder_config = copy.deepcopy(config) + decoder_config.is_decoder = True + decoder_config.num_layers = config.num_decoder_layers + self.decoder = Pop2PianoStack(decoder_config) + + self.lm_head = nn.Linear(config.d_model, config.vocab_size, bias=False) + + # Initialize weights and apply final processing + self.post_init() + + def get_input_embeddings(self): + return self.shared + + def set_input_embeddings(self, new_embeddings): + self.shared = new_embeddings + self.encoder.set_input_embeddings(new_embeddings) + self.decoder.set_input_embeddings(new_embeddings) + + def get_mel_conditioner_outputs( + self, + input_features: torch.FloatTensor, + composer: str, + generation_config: GenerationConfig, + attention_mask: torch.FloatTensor | None = None, + ): + """ + This method is used to concatenate mel conditioner tokens at the front of the input_features in order to + control the type of MIDI token generated by the model. + + Args: + input_features (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`): + input features extracted from the feature extractor. + composer (`str`): + composer token which determines the type of MIDI tokens to be generated. + generation_config (`~generation.GenerationConfig`): + The generation is used to get the composer-feature_token pair. + attention_mask (``, *optional*): + For batched generation `input_features` are padded to have the same shape across all examples. + `attention_mask` helps to determine which areas were padded and which were not. + - 1 for tokens that are **not padded**, + - 0 for tokens that are **padded**. + """ + composer_to_feature_token = generation_config.composer_to_feature_token + if composer not in composer_to_feature_token: + raise ValueError( + f"Please choose a composer from {list(composer_to_feature_token.keys())}. Composer received - {composer}" + ) + composer_value = composer_to_feature_token[composer] + composer_value = torch.tensor(composer_value, device=self.device) + composer_value = composer_value.repeat(input_features.shape[0]) + + embedding_offset = min(composer_to_feature_token.values()) + + input_features = self.mel_conditioner( + feature=input_features, + index_value=composer_value, + embedding_offset=embedding_offset, + ) + if attention_mask is not None: + input_features[~attention_mask[:, 0].bool()] = 0.0 + + # since self.mel_conditioner adds a new array at the front of inputs_embeds we need to do the same for attention_mask to keep the shapes same + attention_mask = torch.concatenate([attention_mask[:, 0].view(-1, 1), attention_mask], axis=1) + return input_features, attention_mask + + return input_features, None + + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.FloatTensor | None = None, + decoder_input_ids: torch.LongTensor | None = None, + decoder_attention_mask: torch.BoolTensor | None = None, + encoder_outputs: tuple[tuple[torch.Tensor]] | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.FloatTensor | None = None, + input_features: torch.FloatTensor | None = None, + decoder_inputs_embeds: torch.FloatTensor | None = None, + labels: torch.LongTensor | None = None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + cache_position: torch.LongTensor | None = None, + **kwargs, + ) -> tuple[torch.FloatTensor] | Seq2SeqLMOutput: + r""" + input_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`): + Indices of input sequence tokens in the vocabulary. Pop2Piano is a model with relative position embeddings + so you should be able to pad the inputs on both the right and the left. Indices can be obtained using + [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and [`PreTrainedTokenizer.__call__`] for detail. + [What are input IDs?](../glossary#input-ids) To know more on how to prepare `input_ids` for pretraining + take a look a [Pop2Piano Training](./Pop2Piano#training). + decoder_input_ids (`torch.LongTensor` of shape `(batch_size, target_sequence_length)`, *optional*): + Indices of decoder input sequence tokens in the vocabulary. Indices can be obtained using + [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and [`PreTrainedTokenizer.__call__`] for details. + [What are decoder input IDs?](../glossary#decoder-input-ids) Pop2Piano uses the `pad_token_id` as the + starting token for `decoder_input_ids` generation. If `past_key_values` is used, optionally only the last + `decoder_input_ids` have to be input (see `past_key_values`). To know more on how to prepare + decoder_attention_mask (`torch.BoolTensor` of shape `(batch_size, target_sequence_length)`, *optional*): + Default behavior: generate a tensor that ignores pad tokens in `decoder_input_ids`. Causal mask will also + be used by default. + labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*): + Labels for computing the sequence classification/regression loss. Indices should be in `[-100, 0, ..., + config.vocab_size - 1]`. All labels set to `-100` are ignored (masked), the loss is only computed for + labels in `[0, ..., config.vocab_size]` + """ + use_cache = use_cache if use_cache is not None else self.config.use_cache + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + if inputs_embeds is not None and input_features is not None: + raise ValueError("Both `inputs_embeds` and `input_features` received! Please provide only one of them") + elif input_features is not None and inputs_embeds is None: + inputs_embeds = input_features + + # Encode if needed (training, first prediction pass) + if encoder_outputs is None: + # Convert encoder inputs in embeddings if needed + encoder_outputs = self.encoder( + input_ids=input_ids, + attention_mask=attention_mask, + inputs_embeds=inputs_embeds, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + elif return_dict and not isinstance(encoder_outputs, BaseModelOutput): + encoder_outputs = BaseModelOutput( + last_hidden_state=encoder_outputs[0], + hidden_states=encoder_outputs[1] if len(encoder_outputs) > 1 else None, + attentions=encoder_outputs[2] if len(encoder_outputs) > 2 else None, + ) + + hidden_states = encoder_outputs[0] + + if labels is not None and decoder_input_ids is None and decoder_inputs_embeds is None: + # get decoder inputs from shifting lm labels to the right + decoder_input_ids = self._shift_right(labels) + + # Decode + decoder_outputs = self.decoder( + input_ids=decoder_input_ids, + attention_mask=decoder_attention_mask, + inputs_embeds=decoder_inputs_embeds, + past_key_values=past_key_values, + encoder_hidden_states=hidden_states, + encoder_attention_mask=attention_mask, + use_cache=use_cache, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + cache_position=cache_position, + ) + + sequence_output = decoder_outputs[0] + + if self.config.tie_word_embeddings: + sequence_output = sequence_output * (self.model_dim**-0.5) + + lm_logits = self.lm_head(sequence_output) + + loss = None + if labels is not None: + loss_fct = CrossEntropyLoss(ignore_index=-100) + loss = loss_fct(lm_logits.view(-1, lm_logits.size(-1)), labels.view(-1)) + + if not return_dict: + output = (lm_logits,) + decoder_outputs[1:] + encoder_outputs + return ((loss,) + output) if loss is not None else output + + return Seq2SeqLMOutput( + loss=loss, + logits=lm_logits, + past_key_values=decoder_outputs.past_key_values, + decoder_hidden_states=decoder_outputs.hidden_states, + decoder_attentions=decoder_outputs.attentions, + cross_attentions=decoder_outputs.cross_attentions, + encoder_last_hidden_state=encoder_outputs.last_hidden_state, + encoder_hidden_states=encoder_outputs.hidden_states, + encoder_attentions=encoder_outputs.attentions, + ) + + @torch.no_grad() + def generate( + self, + input_features, + attention_mask=None, + composer="composer1", + generation_config=None, + **kwargs, + ): + """ + Generates token ids for midi outputs. + + + + Most generation-controlling parameters are set in `generation_config` which, if not passed, will be set to the + model's default generation configuration. You can override any `generation_config` by passing the corresponding + parameters to generate(), e.g. `.generate(inputs, num_beams=4, do_sample=True)`. For an overview of generation + strategies and code examples, check out the [following guide](./generation_strategies). + + + + Parameters: + input_features (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*): + This is the featurized version of audio generated by `Pop2PianoFeatureExtractor`. + attention_mask: + For batched generation `input_features` are padded to have the same shape across all examples. + `attention_mask` helps to determine which areas were padded and which were not. + - 1 for tokens that are **not padded**, + - 0 for tokens that are **padded**. + composer (`str`, *optional*, defaults to `"composer1"`): + This value is passed to `Pop2PianoConcatEmbeddingToMel` to generate different embeddings for each + `"composer"`. Please make sure that the composer value is present in `composer_to_feature_token` in + `generation_config`. For an example please see + https://huggingface.co/sweetcocoa/pop2piano/blob/main/generation_config.json . + generation_config (`~generation.GenerationConfig`, *optional*): + The generation configuration to be used as base parametrization for the generation call. `**kwargs` + passed to generate matching the attributes of `generation_config` will override them. If + `generation_config` is not provided, the default will be used, which had the following loading + priority: 1) from the `generation_config.json` model file, if it exists; 2) from the model + configuration. Please note that unspecified parameters will inherit [`~generation.GenerationConfig`]'s + default values, whose documentation should be checked to parameterize generation. + kwargs: + Ad hoc parametrization of `generate_config` and/or additional model-specific kwargs that will be + forwarded to the `forward` function of the model. If the model is an encoder-decoder model, encoder + specific kwargs should not be prefixed and decoder specific kwargs should be prefixed with *decoder_*. + Return: + [`~utils.ModelOutput`] or `torch.LongTensor`: A [`~utils.ModelOutput`] (if `return_dict_in_generate=True` + or when `config.return_dict_in_generate=True`) or a `torch.FloatTensor`. + Since Pop2Piano is an encoder-decoder model (`model.config.is_encoder_decoder=True`), the possible + [`~utils.ModelOutput`] types are: + - [`~generation.GenerateEncoderDecoderOutput`], + - [`~generation.GenerateBeamEncoderDecoderOutput`] + """ + + if generation_config is None: + generation_config = self.generation_config + generation_config.update(**kwargs) + + # check for composer_to_feature_token + if not hasattr(generation_config, "composer_to_feature_token"): + raise ValueError( + "`composer_to_feature_token` was not found! Please refer to " + "https://huggingface.co/sweetcocoa/pop2piano/blob/main/generation_config.json" + "and parse a dict like that." + ) + + if len(generation_config.composer_to_feature_token) != self.config.composer_vocab_size: + raise ValueError( + "config.composer_vocab_size must be same as the number of keys in " + f"generation_config.composer_to_feature_token! " + f"Found {self.config.composer_vocab_size} vs {len(generation_config.composer_to_feature_token)}." + ) + + # to control the variation of generated MIDI tokens we concatenate mel-conditioner tokens(which depends on composer_token) + # at the front of input_features. + input_features, attention_mask = self.get_mel_conditioner_outputs( + input_features=input_features, + attention_mask=attention_mask, + composer=composer, + generation_config=generation_config, + ) + + return super().generate( + inputs=None, + inputs_embeds=input_features, + attention_mask=attention_mask, + generation_config=generation_config, + **kwargs, + ) + + def prepare_decoder_input_ids_from_labels(self, labels: torch.Tensor): + return self._shift_right(labels) + + +__all__ = ["Pop2PianoForConditionalGeneration", "Pop2PianoPreTrainedModel"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pop2piano/processing_pop2piano.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pop2piano/processing_pop2piano.py new file mode 100644 index 0000000000000000000000000000000000000000..e7588ad148163782b7fbb70b075b75424cfbf5e4 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pop2piano/processing_pop2piano.py @@ -0,0 +1,126 @@ +# Copyright 2023 The HuggingFace Inc. team. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""Processor class for Pop2Piano.""" + +import os + +import numpy as np + +from ...feature_extraction_utils import BatchFeature +from ...processing_utils import ProcessorMixin +from ...tokenization_python import BatchEncoding, PaddingStrategy, TruncationStrategy +from ...utils import TensorType, auto_docstring +from ...utils.import_utils import requires + + +@requires(backends=("essentia", "librosa", "pretty_midi", "scipy", "torch")) +@auto_docstring +class Pop2PianoProcessor(ProcessorMixin): + def __init__(self, feature_extractor, tokenizer): + super().__init__(feature_extractor, tokenizer) + + @auto_docstring + def __call__( + self, + audio: np.ndarray | list[float] | list[np.ndarray] = None, + sampling_rate: int | list[int] | None = None, + steps_per_beat: int = 2, + resample: bool | None = True, + notes: list | TensorType = None, + padding: bool | str | PaddingStrategy = False, + truncation: bool | str | TruncationStrategy = None, + max_length: int | None = None, + pad_to_multiple_of: int | None = None, + verbose: bool = True, + **kwargs, + ) -> BatchFeature | BatchEncoding: + # Since Feature Extractor needs both audio and sampling_rate and tokenizer needs both token_ids and + # feature_extractor_output, we must check for both. + r""" + sampling_rate (`int` or `list[int]`, *optional*): + The sampling rate of the input audio in Hz. This should match the sampling rate used by the feature + extractor. If not provided, the default sampling rate from the processor configuration will be used. + steps_per_beat (`int`, *optional*, defaults to `2`): + The number of time steps per musical beat. This parameter controls the temporal resolution of the + musical representation. A higher value provides finer temporal granularity but increases the sequence + length. Used when processing audio to extract musical features. + notes (`list` or `TensorType`, *optional*): + Pre-extracted musical notes in MIDI format. When provided, the processor skips audio feature extraction + and directly processes the notes through the tokenizer. Each note should be represented as a list or + tensor containing pitch, velocity, and timing information. + """ + if (audio is None and sampling_rate is None) and (notes is None): + raise ValueError( + "You have to specify at least audios and sampling_rate in order to use feature extractor or " + "notes to use the tokenizer part." + ) + + if audio is not None and sampling_rate is not None: + inputs = self.feature_extractor( + audio=audio, + sampling_rate=sampling_rate, + steps_per_beat=steps_per_beat, + resample=resample, + **kwargs, + ) + if notes is not None: + encoded_token_ids = self.tokenizer( + notes=notes, + padding=padding, + truncation=truncation, + max_length=max_length, + pad_to_multiple_of=pad_to_multiple_of, + verbose=verbose, + **kwargs, + ) + + if notes is None: + return inputs + + elif audio is None or sampling_rate is None: + return encoded_token_ids + + else: + inputs["token_ids"] = encoded_token_ids["token_ids"] + return inputs + + def batch_decode( + self, + token_ids, + feature_extractor_output: BatchFeature, + return_midi: bool = True, + ) -> BatchEncoding: + """ + This method uses [`Pop2PianoTokenizer.batch_decode`] method to convert model generated token_ids to midi_notes. + + Please refer to the docstring of the above two methods for more information. + """ + + return self.tokenizer.batch_decode( + token_ids=token_ids, feature_extractor_output=feature_extractor_output, return_midi=return_midi + ) + + def save_pretrained(self, save_directory, **kwargs): + if os.path.isfile(save_directory): + raise ValueError(f"Provided path ({save_directory}) should be a directory, not a file") + os.makedirs(save_directory, exist_ok=True) + return super().save_pretrained(save_directory, **kwargs) + + @classmethod + def from_pretrained(cls, pretrained_model_name_or_path, **kwargs): + args = cls._get_arguments_from_pretrained(pretrained_model_name_or_path, **kwargs) + return cls(*args) + + +__all__ = ["Pop2PianoProcessor"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pop2piano/tokenization_pop2piano.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pop2piano/tokenization_pop2piano.py new file mode 100644 index 0000000000000000000000000000000000000000..115484ac25404e1cdde61adb9524738a5d549cff --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pop2piano/tokenization_pop2piano.py @@ -0,0 +1,714 @@ +# Copyright 2023 The Pop2Piano Authors and The HuggingFace Inc. team. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""Tokenization class for Pop2Piano.""" + +import json +import os + +import numpy as np + +from ...feature_extraction_utils import BatchFeature +from ...tokenization_python import AddedToken, BatchEncoding, PaddingStrategy, PreTrainedTokenizer, TruncationStrategy +from ...utils import TensorType, is_pretty_midi_available, logging, requires_backends, to_numpy +from ...utils.import_utils import requires + + +if is_pretty_midi_available(): + import pretty_midi + +logger = logging.get_logger(__name__) + + +VOCAB_FILES_NAMES = { + "vocab": "vocab.json", +} + + +def token_time_to_note(number, cutoff_time_idx, current_idx): + current_idx += number + if cutoff_time_idx is not None: + current_idx = min(current_idx, cutoff_time_idx) + + return current_idx + + +def token_note_to_note(number, current_velocity, default_velocity, note_onsets_ready, current_idx, notes): + if note_onsets_ready[number] is not None: + # offset with onset + onset_idx = note_onsets_ready[number] + if onset_idx < current_idx: + # Time shift after previous note_on + offset_idx = current_idx + notes.append([onset_idx, offset_idx, number, default_velocity]) + onsets_ready = None if current_velocity == 0 else current_idx + note_onsets_ready[number] = onsets_ready + else: + note_onsets_ready[number] = current_idx + return notes + + +@requires(backends=("pretty_midi", "torch")) +class Pop2PianoTokenizer(PreTrainedTokenizer): + """ + Constructs a Pop2Piano tokenizer. This tokenizer does not require training. + + This tokenizer inherits from [`PreTrainedTokenizer`] which contains most of the main methods. Users should refer to + this superclass for more information regarding those methods. + + Args: + vocab (`str`): + Path to the vocab file which contains the vocabulary. + default_velocity (`int`, *optional*, defaults to 77): + Determines the default velocity to be used while creating midi Notes. + num_bars (`int`, *optional*, defaults to 2): + Determines cutoff_time_idx in for each token. + unk_token (`str` or `tokenizers.AddedToken`, *optional*, defaults to `"-1"`): + The unknown token. A token that is not in the vocabulary cannot be converted to an ID and is set to be this + token instead. + eos_token (`str` or `tokenizers.AddedToken`, *optional*, defaults to 1): + The end of sequence token. + pad_token (`str` or `tokenizers.AddedToken`, *optional*, defaults to 0): + A special token used to make arrays of tokens the same size for batching purpose. Will then be ignored by + attention mechanisms or loss computation. + bos_token (`str` or `tokenizers.AddedToken`, *optional*, defaults to 2): + The beginning of sequence token that was used during pretraining. Can be used a sequence classifier token. + """ + + model_input_names = ["token_ids", "attention_mask"] + vocab_files_names = VOCAB_FILES_NAMES + + def __init__( + self, + vocab, + default_velocity=77, + num_bars=2, + unk_token="-1", + eos_token="1", + pad_token="0", + bos_token="2", + **kwargs, + ): + unk_token = AddedToken(unk_token, lstrip=False, rstrip=False) if isinstance(unk_token, str) else unk_token + eos_token = AddedToken(eos_token, lstrip=False, rstrip=False) if isinstance(eos_token, str) else eos_token + pad_token = AddedToken(pad_token, lstrip=False, rstrip=False) if isinstance(pad_token, str) else pad_token + bos_token = AddedToken(bos_token, lstrip=False, rstrip=False) if isinstance(bos_token, str) else bos_token + + self.default_velocity = default_velocity + self.num_bars = num_bars + + # Load the vocab + with open(vocab, "rb") as file: + self.encoder = json.load(file) + + # create mappings for encoder + self.decoder = {v: k for k, v in self.encoder.items()} + + super().__init__( + unk_token=unk_token, + eos_token=eos_token, + pad_token=pad_token, + bos_token=bos_token, + **kwargs, + ) + + @property + def vocab_size(self): + """Returns the vocabulary size of the tokenizer.""" + return len(self.encoder) + + def get_vocab(self): + """Returns the vocabulary of the tokenizer.""" + return dict(self.encoder, **self.added_tokens_encoder) + + def _convert_id_to_token(self, token_id: int) -> list: + """ + Decodes the token ids generated by the transformer into notes. + + Args: + token_id (`int`): + This denotes the ids generated by the transformers to be converted to Midi tokens. + + Returns: + `List`: A list consists of token_type (`str`) and value (`int`). + """ + + token_type_value = self.decoder.get(token_id, f"{self.unk_token}_TOKEN_TIME") + token_type_value = token_type_value.split("_") + token_type, value = "_".join(token_type_value[1:]), int(token_type_value[0]) + + return [token_type, value] + + def _convert_token_to_id(self, token, token_type="TOKEN_TIME") -> int: + """ + Encodes the Midi tokens to transformer generated token ids. + + Args: + token (`int`): + This denotes the token value. + token_type (`str`): + This denotes the type of the token. There are four types of midi tokens such as "TOKEN_TIME", + "TOKEN_VELOCITY", "TOKEN_NOTE" and "TOKEN_SPECIAL". + + Returns: + `int`: returns the id of the token. + """ + return self.encoder.get(f"{token}_{token_type}", int(self.unk_token)) + + def relative_batch_tokens_ids_to_notes( + self, + tokens: np.ndarray, + beat_offset_idx: int, + bars_per_batch: int, + cutoff_time_idx: int, + ): + """ + Converts relative tokens to notes which are then used to generate pretty midi object. + + Args: + tokens (`numpy.ndarray`): + Tokens to be converted to notes. + beat_offset_idx (`int`): + Denotes beat offset index for each note in generated Midi. + bars_per_batch (`int`): + A parameter to control the Midi output generation. + cutoff_time_idx (`int`): + Denotes the cutoff time index for each note in generated Midi. + """ + + notes = None + + for index in range(len(tokens)): + _tokens = tokens[index] + _start_idx = beat_offset_idx + index * bars_per_batch * 4 + _cutoff_time_idx = cutoff_time_idx + _start_idx + _notes = self.relative_tokens_ids_to_notes( + _tokens, + start_idx=_start_idx, + cutoff_time_idx=_cutoff_time_idx, + ) + + if len(_notes) == 0: + pass + elif notes is None: + notes = _notes + else: + notes = np.concatenate((notes, _notes), axis=0) + + if notes is None: + return [] + return notes + + def relative_batch_tokens_ids_to_midi( + self, + tokens: np.ndarray, + beatstep: np.ndarray, + beat_offset_idx: int = 0, + bars_per_batch: int = 2, + cutoff_time_idx: int = 12, + ): + """ + Converts tokens to Midi. This method calls `relative_batch_tokens_ids_to_notes` method to convert batch tokens + to notes then uses `notes_to_midi` method to convert them to Midi. + + Args: + tokens (`numpy.ndarray`): + Denotes tokens which alongside beatstep will be converted to Midi. + beatstep (`np.ndarray`): + We get beatstep from feature extractor which is also used to get Midi. + beat_offset_idx (`int`, *optional*, defaults to 0): + Denotes beat offset index for each note in generated Midi. + bars_per_batch (`int`, *optional*, defaults to 2): + A parameter to control the Midi output generation. + cutoff_time_idx (`int`, *optional*, defaults to 12): + Denotes the cutoff time index for each note in generated Midi. + """ + beat_offset_idx = 0 if beat_offset_idx is None else beat_offset_idx + notes = self.relative_batch_tokens_ids_to_notes( + tokens=tokens, + beat_offset_idx=beat_offset_idx, + bars_per_batch=bars_per_batch, + cutoff_time_idx=cutoff_time_idx, + ) + midi = self.notes_to_midi(notes, beatstep, offset_sec=beatstep[beat_offset_idx]) + return midi + + # Taken from the original code + # Please see https://github.com/sweetcocoa/pop2piano/blob/fac11e8dcfc73487513f4588e8d0c22a22f2fdc5/midi_tokenizer.py#L257 + def relative_tokens_ids_to_notes(self, tokens: np.ndarray, start_idx: float, cutoff_time_idx: float | None = None): + """ + Converts relative tokens to notes which will then be used to create Pretty Midi objects. + + Args: + tokens (`numpy.ndarray`): + Relative Tokens which will be converted to notes. + start_idx (`float`): + A parameter which denotes the starting index. + cutoff_time_idx (`float`, *optional*): + A parameter used while converting tokens to notes. + """ + words = [self._convert_id_to_token(token) for token in tokens] + + current_idx = start_idx + current_velocity = 0 + note_onsets_ready = [None for i in range(sum(k.endswith("NOTE") for k in self.encoder) + 1)] + notes = [] + for token_type, number in words: + if token_type == "TOKEN_SPECIAL": + if number == 1: + break + elif token_type == "TOKEN_TIME": + current_idx = token_time_to_note( + number=number, cutoff_time_idx=cutoff_time_idx, current_idx=current_idx + ) + elif token_type == "TOKEN_VELOCITY": + current_velocity = number + + elif token_type == "TOKEN_NOTE": + notes = token_note_to_note( + number=number, + current_velocity=current_velocity, + default_velocity=self.default_velocity, + note_onsets_ready=note_onsets_ready, + current_idx=current_idx, + notes=notes, + ) + else: + raise ValueError("Token type not understood!") + + for pitch, note_onset in enumerate(note_onsets_ready): + # force offset if no offset for each pitch + if note_onset is not None: + if cutoff_time_idx is None: + cutoff = note_onset + 1 + else: + cutoff = max(cutoff_time_idx, note_onset + 1) + + offset_idx = max(current_idx, cutoff) + notes.append([note_onset, offset_idx, pitch, self.default_velocity]) + + if len(notes) == 0: + return [] + else: + notes = np.array(notes) + note_order = notes[:, 0] * 128 + notes[:, 1] + notes = notes[note_order.argsort()] + return notes + + def notes_to_midi(self, notes: np.ndarray, beatstep: np.ndarray, offset_sec: int = 0.0): + """ + Converts notes to Midi. + + Args: + notes (`numpy.ndarray`): + This is used to create Pretty Midi objects. + beatstep (`numpy.ndarray`): + This is the extrapolated beatstep that we get from feature extractor. + offset_sec (`int`, *optional*, defaults to 0.0): + This represents the offset seconds which is used while creating each Pretty Midi Note. + """ + + requires_backends(self, ["pretty_midi"]) + + new_pm = pretty_midi.PrettyMIDI(resolution=384, initial_tempo=120.0) + new_inst = pretty_midi.Instrument(program=0) + new_notes = [] + + for onset_idx, offset_idx, pitch, velocity in notes: + new_note = pretty_midi.Note( + velocity=velocity, + pitch=pitch, + start=beatstep[onset_idx] - offset_sec, + end=beatstep[offset_idx] - offset_sec, + ) + new_notes.append(new_note) + new_inst.notes = new_notes + new_pm.instruments.append(new_inst) + new_pm.remove_invalid_notes() + return new_pm + + def save_vocabulary(self, save_directory: str, filename_prefix: str | None = None) -> tuple[str]: + """ + Saves the tokenizer's vocabulary dictionary to the provided save_directory. + + Args: + save_directory (`str`): + A path to the directory where to saved. It will be created if it doesn't exist. + filename_prefix (`Optional[str]`, *optional*): + A prefix to add to the names of the files saved by the tokenizer. + """ + if not os.path.isdir(save_directory): + logger.error(f"Vocabulary path ({save_directory}) should be a directory") + return + + # Save the encoder. + out_vocab_file = os.path.join( + save_directory, (filename_prefix + "-" if filename_prefix else "") + VOCAB_FILES_NAMES["vocab"] + ) + with open(out_vocab_file, "w") as file: + file.write(json.dumps(self.encoder)) + + return (out_vocab_file,) + + def encode_plus( + self, + notes: np.ndarray | list[pretty_midi.Note], + truncation_strategy: TruncationStrategy | None = None, + max_length: int | None = None, + **kwargs, + ) -> BatchEncoding: + r""" + This is the `encode_plus` method for `Pop2PianoTokenizer`. It converts the midi notes to the transformer + generated token ids. It only works on a single batch, to process multiple batches please use + `batch_encode_plus` or `__call__` method. + + Args: + notes (`numpy.ndarray` of shape `[sequence_length, 4]` or `list` of `pretty_midi.Note` objects): + This represents the midi notes. If `notes` is a `numpy.ndarray`: + - Each sequence must have 4 values, they are `onset idx`, `offset idx`, `pitch` and `velocity`. + If `notes` is a `list` containing `pretty_midi.Note` objects: + - Each sequence must have 4 attributes, they are `start`, `end`, `pitch` and `velocity`. + truncation_strategy ([`~tokenization_utils_base.TruncationStrategy`], *optional*): + Indicates the truncation strategy that is going to be used during truncation. + max_length (`int`, *optional*): + Maximum length of the returned list and optionally padding length (see above). + + Returns: + `BatchEncoding` containing the tokens ids. + """ + + requires_backends(self, ["pretty_midi"]) + + # check if notes is a pretty_midi object or not, if yes then extract the attributes and put them into a numpy + # array. + if isinstance(notes[0], pretty_midi.Note): + notes = np.array( + [[each_note.start, each_note.end, each_note.pitch, each_note.velocity] for each_note in notes] + ).reshape(-1, 4) + + # to round up all the values to the closest int values. + notes = np.round(notes).astype(np.int32) + max_time_idx = notes[:, :2].max() + + times = [[] for i in range(max_time_idx + 1)] + for onset, offset, pitch, velocity in notes: + times[onset].append([pitch, velocity]) + times[offset].append([pitch, 0]) + + tokens = [] + current_velocity = 0 + for i, time in enumerate(times): + if len(time) == 0: + continue + tokens.append(self._convert_token_to_id(i, "TOKEN_TIME")) + for pitch, velocity in time: + velocity = int(velocity > 0) + if current_velocity != velocity: + current_velocity = velocity + tokens.append(self._convert_token_to_id(velocity, "TOKEN_VELOCITY")) + tokens.append(self._convert_token_to_id(pitch, "TOKEN_NOTE")) + + total_len = len(tokens) + + # truncation + if truncation_strategy != TruncationStrategy.DO_NOT_TRUNCATE and max_length and total_len > max_length: + tokens, _, _ = self.truncate_sequences( + ids=tokens, + num_tokens_to_remove=total_len - max_length, + truncation_strategy=truncation_strategy, + **kwargs, + ) + + return BatchEncoding({"token_ids": tokens}) + + def batch_encode_plus( + self, + notes: np.ndarray | list[pretty_midi.Note], + truncation_strategy: TruncationStrategy | None = None, + max_length: int | None = None, + **kwargs, + ) -> BatchEncoding: + r""" + This is the `batch_encode_plus` method for `Pop2PianoTokenizer`. It converts the midi notes to the transformer + generated token ids. It works on multiple batches by calling `encode_plus` multiple times in a loop. + + Args: + notes (`numpy.ndarray` of shape `[batch_size, sequence_length, 4]` or `list` of `pretty_midi.Note` objects): + This represents the midi notes. If `notes` is a `numpy.ndarray`: + - Each sequence must have 4 values, they are `onset idx`, `offset idx`, `pitch` and `velocity`. + If `notes` is a `list` containing `pretty_midi.Note` objects: + - Each sequence must have 4 attributes, they are `start`, `end`, `pitch` and `velocity`. + truncation_strategy ([`~tokenization_utils_base.TruncationStrategy`], *optional*): + Indicates the truncation strategy that is going to be used during truncation. + max_length (`int`, *optional*): + Maximum length of the returned list and optionally padding length (see above). + + Returns: + `BatchEncoding` containing the tokens ids. + """ + + encoded_batch_token_ids = [] + for i in range(len(notes)): + encoded_batch_token_ids.append( + self.encode_plus( + notes[i], + truncation_strategy=truncation_strategy, + max_length=max_length, + **kwargs, + )["token_ids"] + ) + + return BatchEncoding({"token_ids": encoded_batch_token_ids}) + + def __call__( + self, + notes: np.ndarray | list[pretty_midi.Note] | list[list[pretty_midi.Note]], + padding: bool | str | PaddingStrategy = False, + truncation: bool | str | TruncationStrategy = None, + max_length: int | None = None, + pad_to_multiple_of: int | None = None, + return_attention_mask: bool | None = None, + return_tensors: str | TensorType | None = None, + verbose: bool = True, + **kwargs, + ) -> BatchEncoding: + r""" + This is the `__call__` method for `Pop2PianoTokenizer`. It converts the midi notes to the transformer generated + token ids. + + Args: + notes (`numpy.ndarray` of shape `[batch_size, max_sequence_length, 4]` or `list` of `pretty_midi.Note` objects): + This represents the midi notes. + + If `notes` is a `numpy.ndarray`: + - Each sequence must have 4 values, they are `onset idx`, `offset idx`, `pitch` and `velocity`. + If `notes` is a `list` containing `pretty_midi.Note` objects: + - Each sequence must have 4 attributes, they are `start`, `end`, `pitch` and `velocity`. + padding (`bool`, `str` or [`~file_utils.PaddingStrategy`], *optional*, defaults to `False`): + Activates and controls padding. Accepts the following values: + + - `True` or `'longest'`: Pad to the longest sequence in the batch (or no padding if only a single + sequence if provided). + - `'max_length'`: Pad to a maximum length specified with the argument `max_length` or to the maximum + acceptable input length for the model if that argument is not provided. + - `False` or `'do_not_pad'` (default): No padding (i.e., can output a batch with sequences of different + lengths). + truncation (`bool`, `str` or [`~tokenization_utils_base.TruncationStrategy`], *optional*, defaults to `False`): + Activates and controls truncation. Accepts the following values: + + - `True` or `'longest_first'`: Truncate to a maximum length specified with the argument `max_length` or + to the maximum acceptable input length for the model if that argument is not provided. This will + truncate token by token, removing a token from the longest sequence in the pair if a pair of + sequences (or a batch of pairs) is provided. + - `'only_first'`: Truncate to a maximum length specified with the argument `max_length` or to the + maximum acceptable input length for the model if that argument is not provided. This will only + truncate the first sequence of a pair if a pair of sequences (or a batch of pairs) is provided. + - `'only_second'`: Truncate to a maximum length specified with the argument `max_length` or to the + maximum acceptable input length for the model if that argument is not provided. This will only + truncate the second sequence of a pair if a pair of sequences (or a batch of pairs) is provided. + - `False` or `'do_not_truncate'` (default): No truncation (i.e., can output batch with sequence lengths + greater than the model maximum admissible input size). + max_length (`int`, *optional*): + Controls the maximum length to use by one of the truncation/padding parameters. If left unset or set to + `None`, this will use the predefined model maximum length if a maximum length is required by one of the + truncation/padding parameters. If the model has no specific maximum input length (like XLNet) + truncation/padding to a maximum length will be deactivated. + pad_to_multiple_of (`int`, *optional*): + If set will pad the sequence to a multiple of the provided value. This is especially useful to enable + the use of Tensor Cores on NVIDIA hardware with compute capability `>= 7.5` (Volta). + return_attention_mask (`bool`, *optional*): + Whether to return the attention mask. If left to the default, will return the attention mask according + to the specific tokenizer's default, defined by the `return_outputs` attribute. + + [What are attention masks?](../glossary#attention-mask) + return_tensors (`str` or [`~file_utils.TensorType`], *optional*): + If set, will return tensors instead of list of python integers. Acceptable values are: + + - `'pt'`: Return PyTorch `torch.Tensor` objects. + - `'np'`: Return Numpy `np.ndarray` objects. + verbose (`bool`, *optional*, defaults to `True`): + Whether or not to print more information and warnings. + + Returns: + `BatchEncoding` containing the token_ids. + """ + + # check if it is batched or not + # it is batched if its a list containing a list of `pretty_midi.Notes` where the outer list contains all the + # batches and the inner list contains all Notes for a single batch. Otherwise if np.ndarray is passed it will be + # considered batched if it has shape of `[batch_size, sequence_length, 4]` or ndim=3. + is_batched = notes.ndim == 3 if isinstance(notes, np.ndarray) else isinstance(notes[0], list) + + # get the truncation and padding strategy + padding_strategy, truncation_strategy, max_length, kwargs = self._get_padding_truncation_strategies( + padding=padding, + truncation=truncation, + max_length=max_length, + pad_to_multiple_of=pad_to_multiple_of, + verbose=verbose, + **kwargs, + ) + + if is_batched: + # If the user has not explicitly mentioned `return_attention_mask` as False, we change it to True + return_attention_mask = True if return_attention_mask is None else return_attention_mask + token_ids = self.batch_encode_plus( + notes=notes, + truncation_strategy=truncation_strategy, + max_length=max_length, + **kwargs, + ) + else: + token_ids = self.encode_plus( + notes=notes, + truncation_strategy=truncation_strategy, + max_length=max_length, + **kwargs, + ) + + # since we already have truncated sequnences we are just left to do padding + token_ids = self.pad( + token_ids, + padding=padding_strategy, + max_length=max_length, + pad_to_multiple_of=pad_to_multiple_of, + return_attention_mask=return_attention_mask, + return_tensors=return_tensors, + verbose=verbose, + ) + + return token_ids + + def batch_decode( + self, + token_ids, + feature_extractor_output: BatchFeature, + return_midi: bool = True, + ): + r""" + This is the `batch_decode` method for `Pop2PianoTokenizer`. It converts the token_ids generated by the + transformer to midi_notes and returns them. + + Args: + token_ids (`Union[np.ndarray, torch.Tensor]`): + Output token_ids of `Pop2PianoConditionalGeneration` model. + feature_extractor_output (`BatchFeature`): + Denotes the output of `Pop2PianoFeatureExtractor.__call__`. It must contain `"beatstep"` and + `"extrapolated_beatstep"`. Also `"attention_mask_beatsteps"` and + `"attention_mask_extrapolated_beatstep"` + should be present if they were returned by the feature extractor. + return_midi (`bool`, *optional*, defaults to `True`): + Whether to return midi object or not. + Returns: + If `return_midi` is True: + - `BatchEncoding` containing both `notes` and `pretty_midi.pretty_midi.PrettyMIDI` objects. + If `return_midi` is False: + - `BatchEncoding` containing `notes`. + """ + + # check if they have attention_masks(attention_mask, attention_mask_beatsteps, attention_mask_extrapolated_beatstep) or not + attention_masks_present = bool( + hasattr(feature_extractor_output, "attention_mask") + and hasattr(feature_extractor_output, "attention_mask_beatsteps") + and hasattr(feature_extractor_output, "attention_mask_extrapolated_beatstep") + ) + + # if we are processing batched inputs then we must need attention_masks + if not attention_masks_present and feature_extractor_output["beatsteps"].shape[0] > 1: + raise ValueError( + "attention_mask, attention_mask_beatsteps and attention_mask_extrapolated_beatstep must be present " + "for batched inputs! But one of them were not present." + ) + + # check for length mismatch between inputs_embeds, beatsteps and extrapolated_beatstep + if attention_masks_present: + # since we know about the number of examples in token_ids from attention_mask + if ( + sum(feature_extractor_output["attention_mask"][:, 0] == 0) + != feature_extractor_output["beatsteps"].shape[0] + or feature_extractor_output["beatsteps"].shape[0] + != feature_extractor_output["extrapolated_beatstep"].shape[0] + ): + raise ValueError( + "Length mistamtch between token_ids, beatsteps and extrapolated_beatstep! Found " + f"token_ids length - {token_ids.shape[0]}, beatsteps shape - {feature_extractor_output['beatsteps'].shape[0]} " + f"and extrapolated_beatsteps shape - {feature_extractor_output['extrapolated_beatstep'].shape[0]}" + ) + if feature_extractor_output["attention_mask"].shape[0] != token_ids.shape[0]: + raise ValueError( + f"Found attention_mask of length - {feature_extractor_output['attention_mask'].shape[0]} but token_ids of length - {token_ids.shape[0]}" + ) + else: + # if there is no attention mask present then it's surely a single example + if ( + feature_extractor_output["beatsteps"].shape[0] != 1 + or feature_extractor_output["extrapolated_beatstep"].shape[0] != 1 + ): + raise ValueError( + "Length mistamtch of beatsteps and extrapolated_beatstep! Since attention_mask is not present the number of examples must be 1, " + f"But found beatsteps length - {feature_extractor_output['beatsteps'].shape[0]}, extrapolated_beatsteps length - {feature_extractor_output['extrapolated_beatstep'].shape[0]}." + ) + + if attention_masks_present: + # check for zeros(since token_ids are separated by zero arrays) + batch_idx = np.where(feature_extractor_output["attention_mask"][:, 0] == 0)[0] + else: + batch_idx = [token_ids.shape[0]] + + notes_list = [] + pretty_midi_objects_list = [] + start_idx = 0 + for index, end_idx in enumerate(batch_idx): + each_tokens_ids = token_ids[start_idx:end_idx] + # check where the whole example ended by searching for eos_token_id and getting the upper bound + each_tokens_ids = each_tokens_ids[:, : np.max(np.where(each_tokens_ids == int(self.eos_token))[1]) + 1] + beatsteps = feature_extractor_output["beatsteps"][index] + extrapolated_beatstep = feature_extractor_output["extrapolated_beatstep"][index] + + # if attention mask is present then mask out real array/tensor + if attention_masks_present: + attention_mask_beatsteps = feature_extractor_output["attention_mask_beatsteps"][index] + attention_mask_extrapolated_beatstep = feature_extractor_output[ + "attention_mask_extrapolated_beatstep" + ][index] + beatsteps = beatsteps[: np.max(np.where(attention_mask_beatsteps == 1)[0]) + 1] + extrapolated_beatstep = extrapolated_beatstep[ + : np.max(np.where(attention_mask_extrapolated_beatstep == 1)[0]) + 1 + ] + + each_tokens_ids = to_numpy(each_tokens_ids) + beatsteps = to_numpy(beatsteps) + extrapolated_beatstep = to_numpy(extrapolated_beatstep) + + pretty_midi_object = self.relative_batch_tokens_ids_to_midi( + tokens=each_tokens_ids, + beatstep=extrapolated_beatstep, + bars_per_batch=self.num_bars, + cutoff_time_idx=(self.num_bars + 1) * 4, + ) + + for note in pretty_midi_object.instruments[0].notes: + note.start += beatsteps[0] + note.end += beatsteps[0] + notes_list.append(note) + + pretty_midi_objects_list.append(pretty_midi_object) + start_idx += end_idx + 1 # 1 represents the zero array + + if return_midi: + return BatchEncoding({"notes": notes_list, "pretty_midi_objects": pretty_midi_objects_list}) + + return BatchEncoding({"notes": notes_list}) + + +__all__ = ["Pop2PianoTokenizer"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pp_doclayout_v2/__init__.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pp_doclayout_v2/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..da1f7a82315eabd9e25ba7dae0610ac727a88d01 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pp_doclayout_v2/__init__.py @@ -0,0 +1,30 @@ +# Copyright 2026 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + + +from typing import TYPE_CHECKING + +from ...utils import _LazyModule +from ...utils.import_utils import define_import_structure + + +if TYPE_CHECKING: + from .configuration_pp_doclayout_v2 import * + from .image_processing_pp_doclayout_v2_fast import * + from .modeling_pp_doclayout_v2 import * +else: + import sys + + _file = globals()["__file__"] + sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__) diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pp_doclayout_v2/configuration_pp_doclayout_v2.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pp_doclayout_v2/configuration_pp_doclayout_v2.py new file mode 100644 index 0000000000000000000000000000000000000000..983c96ef564da84c0a9458c006c56c8530f64e72 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pp_doclayout_v2/configuration_pp_doclayout_v2.py @@ -0,0 +1,415 @@ +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# This file was automatically generated from src/transformers/models/pp_doclayout_v2/modular_pp_doclayout_v2.py. +# Do NOT edit this file manually as any edits will be overwritten by the generation of +# the file from the modular. If any change should be done, please apply the change to the +# modular_pp_doclayout_v2.py file directly. One of our CI enforces this. +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# Copyright 2026 The PaddlePaddle Team and The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +from ...backbone_utils import consolidate_backbone_kwargs_to_config +from ...configuration_utils import PreTrainedConfig +from ..auto import AutoConfig + + +class PPDocLayoutV2ReadingOrderConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`PPDocLayoutV2ReadingOrder`]. + + It is used to instantiate the reading order sub-module of the PP-DocLayoutV2 model. This configuration defines the architecture and hyperparameters specific to the reading order detection task within the larger PP-DocLayoutV2 framework. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + hidden_size (`int`, *optional*, defaults to 512): + Dimension of the encoder layers and the pooled layer. + num_attention_heads (`int`, *optional*, defaults to 8): + Number of attention heads for each attention layer. + attention_probs_dropout_prob (`float`, *optional*, defaults to 0.1): + The dropout ratio for the attention probabilities. + has_relative_attention_bias (`bool`, *optional*, defaults to `True`): + Whether or not to use a relative attention bias in the self-attention mechanism. + has_spatial_attention_bias (`bool`, *optional*, defaults to `True`): + Whether or not to use a spatial attention bias in the self-attention mechanism. + layer_norm_eps (`float`, *optional*, defaults to 1e-05): + The epsilon used by the layer normalization layers. + hidden_dropout_prob (`float`, *optional*, defaults to 0.1): + The dropout probability for all fully connected layers in the embeddings, encoder, and pooler. + intermediate_size (`int`, *optional*, defaults to 2048): + Dimension of the "intermediate" (i.e., feed-forward) layer in the Transformer encoder. + hidden_act (`str` or `function`, *optional*, defaults to `"gelu"`): + The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`, + `"relu"`, `"silu"` and `"gelu_new"` are supported. + num_hidden_layers (`int`, *optional*, defaults to 6): + Number of the hidden layers. + rel_pos_bins (`int`, *optional*, defaults to 32): + The number of relative position bins to be used in the self-attention mechanism. + max_rel_pos (`int`, *optional*, defaults to 128): + The maximum number of relative positions to be used in the self-attention mechanism. + rel_2d_pos_bins (`int`, *optional*, defaults to 64): + The number of 2D relative position bins in the self-attention mechanism. + max_rel_2d_pos (`int`, *optional*, defaults to 256): + The maximum number of relative 2D positions in the self-attention mechanism. + max_position_embeddings (`int`, *optional*, defaults to 514): + The maximum sequence length that this model might ever be used with. Typically set this to something large + just in case (e.g., 512 or 1024 or 2048). + max_2d_position_embeddings (`int`, *optional*, defaults to 1024): + The maximum value that the 2D position embedding might ever be used with. Typically set this to something + large just in case (e.g., 1024). + type_vocab_size (`int`, *optional*, defaults to 1): + The vocabulary size of the `token_type_ids`. + vocab_size (`int`, *optional*, defaults to 4): + Vocabulary size of the model. Defines the number of different tokens that can be represented by the `inputs_ids`. + initializer_range (`float`, *optional*, defaults to 0.01): + The standard deviation of the truncated_normal_initializer for initializing all weight matrices. + start_token_id (`int`, *optional*, defaults to 0): + Token id representing the start of a sequence. + pad_token_id (`int`, *optional*, defaults to 1): + Token id used for padding the input sequences. + end_token_id (`int`, *optional*, defaults to 2): + Token id representing the end of a sequence. + pred_token_id (`int`, *optional*, defaults to 3): + Token id representing valid prediction positions (placeholders) in the sequence. + coordinate_size (`int`, *optional*, defaults to 171): + Dimension of the coordinate embeddings. + shape_size (`int`, *optional*, defaults to 170): + Dimension of the width and height embeddings. + num_classes (`int`, *optional*, defaults to 20): + Number of labels or classes for the layout elements. + relation_bias_embed_dim (`int`, *optional*, defaults to 16): + Embedding dimension for the relation bias. + relation_bias_theta (`float`, *optional*, defaults to 10000): + Temperature parameter used for relation bias scaling. + relation_bias_scale (`float`, *optional*, defaults to 100): + Scale parameter for the relation bias. + global_pointer_head_size (`int`, *optional*, defaults to 64): + The size of the global pointer head. + gp_dropout_value (`float`, *optional*, defaults to 0.0): + The dropout probability in the global pointer head. + """ + + def __init__( + self, + hidden_size=512, + num_attention_heads=8, + attention_probs_dropout_prob=0.1, + has_relative_attention_bias=False, + has_spatial_attention_bias=True, + layer_norm_eps=1e-5, + hidden_dropout_prob=0.1, + intermediate_size=2048, + hidden_act="gelu", + num_hidden_layers=6, + rel_pos_bins=32, + max_rel_pos=128, + rel_2d_pos_bins=64, + max_rel_2d_pos=256, + max_position_embeddings=514, + max_2d_position_embeddings=1024, + type_vocab_size=1, + vocab_size=4, + initializer_range=0.01, + start_token_id=0, + pad_token_id=1, + end_token_id=2, + pred_token_id=3, + coordinate_size=171, + shape_size=170, + num_classes=20, + relation_bias_embed_dim=16, + relation_bias_theta=10000, + relation_bias_scale=100, + global_pointer_head_size=64, + gp_dropout_value=0.0, + **kwargs, + ): + self.hidden_size = hidden_size + self.num_attention_heads = num_attention_heads + self.attention_probs_dropout_prob = attention_probs_dropout_prob + self.has_relative_attention_bias = has_relative_attention_bias + self.has_spatial_attention_bias = has_spatial_attention_bias + self.layer_norm_eps = layer_norm_eps + self.hidden_dropout_prob = hidden_dropout_prob + self.intermediate_size = intermediate_size + self.hidden_act = hidden_act + self.num_hidden_layers = num_hidden_layers + self.rel_pos_bins = rel_pos_bins + self.max_rel_pos = max_rel_pos + self.rel_2d_pos_bins = rel_2d_pos_bins + self.max_rel_2d_pos = max_rel_2d_pos + self.max_position_embeddings = max_position_embeddings + self.max_2d_position_embeddings = max_2d_position_embeddings + self.type_vocab_size = type_vocab_size + self.vocab_size = vocab_size + self.initializer_range = initializer_range + self.start_token_id = start_token_id + self.pad_token_id = pad_token_id + self.end_token_id = end_token_id + self.pred_token_id = pred_token_id + self.coordinate_size = coordinate_size + self.shape_size = shape_size + self.num_classes = num_classes + self.relation_bias_embed_dim = relation_bias_embed_dim + self.relation_bias_theta = relation_bias_theta + self.relation_bias_scale = relation_bias_scale + self.global_pointer_head_size = global_pointer_head_size + self.gp_dropout_value = gp_dropout_value + + super().__init__(**kwargs) + + +class PPDocLayoutV2Config(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`PP-DocLayoutV2`]. It is used to instantiate a + PP-DocLayoutV2 model according to the specified arguments, defining the model architecture. Instantiating a configuration + with the defaults will yield a similar configuration to that of the PP-DocLayoutV2 + [PaddlePaddle/PP-DocLayoutV2_safetensors](https://huggingface.co/PaddlePaddle/PP-DocLayoutV2_safetensors) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + initializer_range (`float`, *optional*, defaults to 0.01): + The standard deviation of the truncated_normal_initializer for initializing all weight matrices. + initializer_bias_prior_prob (`float`, *optional*): + The prior probability used by the bias initializer to initialize biases for `enc_score_head` and `class_embed`. + If `None`, `prior_prob` computed as `prior_prob = 1 / (num_labels + 1)` while initializing model weights. + layer_norm_eps (`float`, *optional*, defaults to 1e-05): + The epsilon used by the layer normalization layers. + batch_norm_eps (`float`, *optional*, defaults to 1e-05): + The epsilon used by the batch normalization layers. + backbone_config (`Union[dict, "PreTrainedConfig"]`, *optional*, defaults to `RTDetrResNetConfig()`): + The configuration of the backbone model. + freeze_backbone_batch_norms (`bool`, *optional*, defaults to `True`): + Whether to freeze the batch normalization layers in the backbone. + encoder_hidden_dim (`int`, *optional*, defaults to 256): + Dimension of the layers in hybrid encoder. + encoder_in_channels (`list`, *optional*, defaults to `[512, 1024, 2048]`): + Multi level features input for encoder. + feat_strides (`list[int]`, *optional*, defaults to `[8, 16, 32]`): + Strides used in each feature map. + encoder_layers (`int`, *optional*, defaults to 1): + Total of layers to be used by the encoder. + encoder_ffn_dim (`int`, *optional*, defaults to 1024): + Dimension of the "intermediate" (often named feed-forward) layer in decoder. + encoder_attention_heads (`int`, *optional*, defaults to 8): + Number of attention heads for each attention layer in the Transformer encoder. + dropout (`float`, *optional*, defaults to 0.0): + The ratio for all dropout layers. + activation_dropout (`float`, *optional*, defaults to 0.0): + The dropout ratio for activations inside the fully connected layer. + encode_proj_layers (`list[int]`, *optional*, defaults to `[2]`): + Indexes of the projected layers to be used in the encoder. + positional_encoding_temperature (`int`, *optional*, defaults to 10000): + The temperature parameter used to create the positional encodings. + encoder_activation_function (`str`, *optional*, defaults to `"gelu"`): + The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`, + `"relu"`, `"silu"` and `"gelu_new"` are supported. + activation_function (`str`, *optional*, defaults to `"silu"`): + The non-linear activation function (function or string) in the general layer. If string, `"gelu"`, + `"relu"`, `"silu"` and `"gelu_new"` are supported. + eval_size (`tuple[int, int]`, *optional*): + Height and width used to computes the effective height and width of the position embeddings after taking + into account the stride. + normalize_before (`bool`, *optional*, defaults to `False`): + Determine whether to apply layer normalization in the transformer encoder layer before self-attention and + feed-forward modules. + hidden_expansion (`float`, *optional*, defaults to 1.0): + Expansion ratio to enlarge the dimension size of RepVGGBlock and CSPRepLayer. + d_model (`int`, *optional*, defaults to 256): + Dimension of the layers exclude hybrid encoder. + num_queries (`int`, *optional*, defaults to 300): + Number of object queries. + decoder_in_channels (`list`, *optional*, defaults to `[256, 256, 256]`): + Multi level features dimension for decoder + decoder_ffn_dim (`int`, *optional*, defaults to 1024): + Dimension of the "intermediate" (often named feed-forward) layer in decoder. + num_feature_levels (`int`, *optional*, defaults to 3): + The number of input feature levels. + decoder_n_points (`int`, *optional*, defaults to 4): + The number of sampled keys in each feature level for each attention head in the decoder. + decoder_layers (`int`, *optional*, defaults to 6): + Number of decoder layers. + decoder_attention_heads (`int`, *optional*, defaults to 8): + Number of attention heads for each attention layer in the Transformer decoder. + decoder_activation_function (`str`, *optional*, defaults to `"relu"`): + The non-linear activation function (function or string) in the decoder. If string, `"gelu"`, + `"relu"`, `"silu"` and `"gelu_new"` are supported. + attention_dropout (`float`, *optional*, defaults to 0.0): + The dropout ratio for the attention probabilities. + num_denoising (`int`, *optional*, defaults to 100): + The total number of denoising tasks or queries to be used for contrastive denoising. + label_noise_ratio (`float`, *optional*, defaults to 0.5): + The fraction of denoising labels to which random noise should be added. + box_noise_scale (`float`, *optional*, defaults to 1.0): + Scale or magnitude of noise to be added to the bounding boxes. + learn_initial_query (`bool`, *optional*, defaults to `False`): + Indicates whether the initial query embeddings for the decoder should be learned during training + anchor_image_size (`tuple[int, int]`, *optional*): + Height and width of the input image used during evaluation to generate the bounding box anchors. If None, automatic generate anchor is applied. + disable_custom_kernels (`bool`, *optional*, defaults to `True`): + Whether to disable custom kernels. + is_encoder_decoder (`bool`, *optional*, defaults to `True`): + Whether the architecture has an encoder decoder structure. + class_thresholds (`list[float]`, *optional*): + The thresholds for each label. + class_order (`list[int]`, *optional*): + The priority for each label. + reading_order_config (`dict`, *optional*): + The configuration of a `PPDocLayoutV2ReadingOrder`. + + Examples: + + ```python + >>> from transformers import PPDocLayoutV2Config, PPDocLayoutV2ForObjectDetection + + >>> # Initializing a PP-DocLayoutV2 configuration + >>> configuration = PPDocLayoutV2Config() + + >>> # Initializing a model (with random weights) from the configuration + >>> model = PPDocLayoutV2ForObjectDetection(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "pp_doclayout_v2" + sub_configs = {"backbone_config": AutoConfig, "reading_order_config": PPDocLayoutV2ReadingOrderConfig} + + layer_types = ("basic", "bottleneck") + attribute_map = { + "hidden_size": "d_model", + "num_attention_heads": "encoder_attention_heads", + } + + def __init__( + self, + initializer_range=0.01, + initializer_bias_prior_prob=None, + layer_norm_eps=1e-5, + batch_norm_eps=1e-5, + # backbone + backbone_config=None, + freeze_backbone_batch_norms=True, + # encoder HybridEncoder + encoder_hidden_dim=256, + encoder_in_channels=[512, 1024, 2048], + feat_strides=[8, 16, 32], + encoder_layers=1, + encoder_ffn_dim=1024, + encoder_attention_heads=8, + dropout=0.0, + activation_dropout=0.0, + encode_proj_layers=[2], + positional_encoding_temperature=10000, + encoder_activation_function="gelu", + activation_function="silu", + eval_size=None, + normalize_before=False, + hidden_expansion=1.0, + # decoder PPDocLayoutV2Transformer + d_model=256, + num_queries=300, + decoder_in_channels=[256, 256, 256], + decoder_ffn_dim=1024, + num_feature_levels=3, + decoder_n_points=4, + decoder_layers=6, + decoder_attention_heads=8, + decoder_activation_function="relu", + attention_dropout=0.0, + num_denoising=100, + label_noise_ratio=0.5, + box_noise_scale=1.0, + learn_initial_query=False, + anchor_image_size=None, + disable_custom_kernels=True, + is_encoder_decoder=True, + # label + class_thresholds=None, + class_order=None, + reading_order_config=None, + **kwargs, + ): + self.initializer_range = initializer_range + self.initializer_bias_prior_prob = initializer_bias_prior_prob + self.layer_norm_eps = layer_norm_eps + self.batch_norm_eps = batch_norm_eps + + if isinstance(reading_order_config, dict): + self.reading_order_config = self.sub_configs["reading_order_config"](**reading_order_config) + elif reading_order_config is None: + self.reading_order_config = self.sub_configs["reading_order_config"]() + + backbone_config, kwargs = consolidate_backbone_kwargs_to_config( + backbone_config=backbone_config, + default_config_type="hgnet_v2", + default_config_kwargs={ + "arch": "L", + "return_idx": [1, 2, 3], + "freeze_stem_only": True, + "freeze_at": 0, + "freeze_norm": True, + "lr_mult_list": [0, 0.05, 0.05, 0.05, 0.05], + "out_features": ["stage2", "stage3", "stage4"], + }, + **kwargs, + ) + + self.backbone_config = backbone_config + self.freeze_backbone_batch_norms = freeze_backbone_batch_norms + + # ---- encoder ---- + self.encoder_hidden_dim = encoder_hidden_dim + self.encoder_in_channels = list(encoder_in_channels) + self.feat_strides = list(feat_strides) + self.encoder_layers = encoder_layers + self.encoder_ffn_dim = encoder_ffn_dim + self.encoder_attention_heads = encoder_attention_heads + self.dropout = dropout + self.activation_dropout = activation_dropout + self.encode_proj_layers = list(encode_proj_layers) + self.positional_encoding_temperature = positional_encoding_temperature + self.encoder_activation_function = encoder_activation_function + self.activation_function = activation_function + self.eval_size = list(eval_size) if eval_size is not None else None + self.normalize_before = normalize_before + self.hidden_expansion = hidden_expansion + + # ---- decoder ---- + self.d_model = d_model + self.num_queries = num_queries + self.decoder_in_channels = list(decoder_in_channels) + self.decoder_ffn_dim = decoder_ffn_dim + self.num_feature_levels = num_feature_levels + self.decoder_n_points = decoder_n_points + self.decoder_layers = decoder_layers + self.decoder_attention_heads = decoder_attention_heads + self.decoder_activation_function = decoder_activation_function + self.attention_dropout = attention_dropout + self.num_denoising = num_denoising + self.label_noise_ratio = label_noise_ratio + self.box_noise_scale = box_noise_scale + self.learn_initial_query = learn_initial_query + self.anchor_image_size = list(anchor_image_size) if anchor_image_size is not None else None + self.disable_custom_kernels = disable_custom_kernels + + self.class_thresholds = class_thresholds + self.class_order = class_order + + super().__init__(is_encoder_decoder=is_encoder_decoder, **kwargs) + + +__all__ = ["PPDocLayoutV2Config"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pp_doclayout_v2/image_processing_pp_doclayout_v2_fast.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pp_doclayout_v2/image_processing_pp_doclayout_v2_fast.py new file mode 100644 index 0000000000000000000000000000000000000000..4e811e92731169ef45e04e9c98f95bc00ab1abd2 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pp_doclayout_v2/image_processing_pp_doclayout_v2_fast.py @@ -0,0 +1,195 @@ +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# This file was automatically generated from src/transformers/models/pp_doclayout_v2/modular_pp_doclayout_v2.py. +# Do NOT edit this file manually as any edits will be overwritten by the generation of +# the file from the modular. If any change should be done, please apply the change to the +# modular_pp_doclayout_v2.py file directly. One of our CI enforces this. +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# Copyright 2026 The PaddlePaddle Team and The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +from typing import Optional + +import torch +import torchvision.transforms.v2.functional as tvF + +from ...image_processing_utils_fast import BaseImageProcessorFast, BatchFeature +from ...image_transforms import group_images_by_shape, reorder_images +from ...image_utils import PILImageResampling, SizeDict +from ...utils import auto_docstring +from ...utils.generic import TensorType + + +@auto_docstring +class PPDocLayoutV2ImageProcessorFast(BaseImageProcessorFast): + resample = PILImageResampling.BICUBIC + image_mean = [0, 0, 0] + image_std = [1, 1, 1] + size = {"height": 800, "width": 800} + do_resize = True + do_rescale = True + do_normalize = True + + # We require `self.resize(..., antialias=False)` to approximate the output of `cv2.resize` + def _preprocess( + self, + images: list["torch.Tensor"], + do_resize: bool, + size: SizeDict, + interpolation: Optional["tvF.InterpolationMode"], + do_center_crop: bool, + crop_size: SizeDict, + do_rescale: bool, + rescale_factor: float, + do_normalize: bool, + image_mean: float | list[float] | None, + image_std: float | list[float] | None, + do_pad: bool | None, + pad_size: SizeDict | None, + disable_grouping: bool | None, + return_tensors: str | TensorType | None, + **kwargs, + ) -> BatchFeature: + # Group images by size for batched resizing + grouped_images, grouped_images_index = group_images_by_shape(images, disable_grouping=disable_grouping) + resized_images_grouped = {} + for shape, stacked_images in grouped_images.items(): + if do_resize: + stacked_images = self.resize( + image=stacked_images, size=size, interpolation=interpolation, antialias=False + ) + resized_images_grouped[shape] = stacked_images + resized_images = reorder_images(resized_images_grouped, grouped_images_index) + + # Group images by size for further processing + # Needed in case do_resize is False, or resize returns images with different sizes + grouped_images, grouped_images_index = group_images_by_shape(resized_images, disable_grouping=disable_grouping) + processed_images_grouped = {} + for shape, stacked_images in grouped_images.items(): + if do_center_crop: + stacked_images = self.center_crop(stacked_images, crop_size) + # Fused rescale and normalize + stacked_images = self.rescale_and_normalize( + stacked_images, do_rescale, rescale_factor, do_normalize, image_mean, image_std + ) + processed_images_grouped[shape] = stacked_images + processed_images = reorder_images(processed_images_grouped, grouped_images_index) + + if do_pad: + processed_images = self.pad(processed_images, pad_size=pad_size, disable_grouping=disable_grouping) + + return BatchFeature(data={"pixel_values": processed_images}, tensor_type=return_tensors) + + def _get_order_seqs(self, order_logits): + """ + Computes the order sequences for a batch of inputs based on logits. + + This function takes in the order logits, calculates order scores using a sigmoid activation, + and determines the order sequences by ranking the votes derived from the scores. + + Args: + order_logits (`torch.FloatTensor` of shape `(batch_size, num_queries, num_queries)`): + Stacked order logits. + + Returns: + torch.Tensor: A tensor of shape `(batch_size, num_queries)`: + Containing the computed order sequences for each input in the batch. Each row represents the ranked order of elements for the corresponding input in the batch. + """ + order_scores = torch.sigmoid(order_logits) + batch_size, sequence_length, _ = order_scores.shape + + order_votes = order_scores.triu(diagonal=1).sum(dim=1) + (1.0 - order_scores.transpose(1, 2)).tril( + diagonal=-1 + ).sum(dim=1) + + order_pointers = torch.argsort(order_votes, dim=1) + order_seq = torch.empty_like(order_pointers) + ranks = torch.arange(sequence_length, device=order_pointers.device, dtype=order_pointers.dtype).expand( + batch_size, -1 + ) + order_seq.scatter_(1, order_pointers, ranks) + + return order_seq + + def extract_custom_vertices(self): + raise AttributeError("Not needed for PPDocLayoutV2") + + def post_process_object_detection( + self, + outputs, + threshold: float = 0.5, + target_sizes: TensorType | list[tuple] | None = None, + ): + """ + Converts the raw output of [`DetrForObjectDetection`] into final bounding boxes in (top_left_x, top_left_y, + bottom_right_x, bottom_right_y) format. Only supports PyTorch. + + PPDocLayoutV2 is identical to PPDocLayoutV3, except that it does not return `polygon_points`. + + Args: + outputs ([`DetrObjectDetectionOutput`]): + Raw outputs of the model. + Returns: + `list[Dict]`: A list of dictionaries, each dictionary containing the scores, labels and boxes for an image + in the batch as predicted by the model. + """ + boxes = outputs.pred_boxes + logits = outputs.logits + order_logits = outputs.order_logits + + order_seqs = self._get_order_seqs(order_logits) + + box_centers, box_dims = torch.split(boxes, 2, dim=-1) + top_left_coords = box_centers - 0.5 * box_dims + bottom_right_coords = box_centers + 0.5 * box_dims + boxes = torch.cat([top_left_coords, bottom_right_coords], dim=-1) + + if target_sizes is not None: + if len(logits) != len(target_sizes): + raise ValueError( + "Make sure that you pass in as many target sizes as the batch dimension of the logits" + ) + if isinstance(target_sizes, list): + img_height, img_width = torch.as_tensor(target_sizes).unbind(1) + else: + img_height, img_width = target_sizes.unbind(1) + scale_factor = torch.stack([img_width, img_height, img_width, img_height], dim=1).to(boxes.device) + boxes = boxes * scale_factor[:, None, :] + + num_top_queries = logits.shape[1] + num_classes = logits.shape[2] + + scores = torch.nn.functional.sigmoid(logits) + scores, index = torch.topk(scores.flatten(1), num_top_queries, dim=-1) + labels = index % num_classes + index = index // num_classes + boxes = boxes.gather(dim=1, index=index.unsqueeze(-1).repeat(1, 1, boxes.shape[-1])) + order_seqs = order_seqs.gather(dim=1, index=index) + + results = [] + for score, label, box, order_seq in zip(scores, labels, boxes, order_seqs): + order_seq = order_seq[score >= threshold] + order_seq, indices = torch.sort(order_seq) + results.append( + { + "scores": score[score >= threshold][indices], + "labels": label[score >= threshold][indices], + "boxes": box[score >= threshold][indices], + "order_seq": order_seq, + } + ) + + return results + + +__all__ = ["PPDocLayoutV2ImageProcessorFast"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pp_doclayout_v2/modeling_pp_doclayout_v2.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pp_doclayout_v2/modeling_pp_doclayout_v2.py new file mode 100644 index 0000000000000000000000000000000000000000..739564147b76be72a672551f73db77990aa6fe08 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pp_doclayout_v2/modeling_pp_doclayout_v2.py @@ -0,0 +1,2522 @@ +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# This file was automatically generated from src/transformers/models/pp_doclayout_v2/modular_pp_doclayout_v2.py. +# Do NOT edit this file manually as any edits will be overwritten by the generation of +# the file from the modular. If any change should be done, please apply the change to the +# modular_pp_doclayout_v2.py file directly. One of our CI enforces this. +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# Copyright 2026 The PaddlePaddle Team and The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import math +import warnings +from collections.abc import Callable +from dataclasses import dataclass +from typing import Optional + +import torch +import torch.nn.functional as F +from torch import Tensor, nn + +from ... import initialization as init +from ...activations import ACT2CLS, ACT2FN +from ...backbone_utils import load_backbone +from ...image_transforms import center_to_corners_format, corners_to_center_format +from ...integrations import use_kernel_forward_from_hub +from ...masking_utils import create_bidirectional_mask +from ...modeling_layers import GradientCheckpointingLayer +from ...modeling_outputs import BaseModelOutput +from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel +from ...processing_utils import Unpack +from ...pytorch_utils import apply_chunking_to_forward, compile_compatible_method_lru_cache +from ...utils import ( + ModelOutput, + TransformersKwargs, + auto_docstring, + can_return_tuple, + torch_compilable_check, + torch_int, +) +from ...utils.generic import merge_with_config_defaults +from ...utils.output_capturing import capture_outputs +from .configuration_pp_doclayout_v2 import PPDocLayoutV2Config + + +class PPDocLayoutV2GlobalPointer(nn.Module): + def __init__(self, config): + super().__init__() + self.head_size = config.global_pointer_head_size + self.dense = nn.Linear(config.hidden_size, self.head_size * 2) + self.dropout = nn.Dropout(config.gp_dropout_value) + + def forward(self, inputs): + batch_size, sequence_length, _ = inputs.shape + query_key_projection = self.dense(inputs).reshape(batch_size, sequence_length, 2, self.head_size) + query_key_projection = self.dropout(query_key_projection) + queries, keys = torch.unbind(query_key_projection, dim=2) + + logits = (queries @ keys.transpose(-2, -1)) / (self.head_size**0.5) + mask = torch.tril(torch.ones(sequence_length, sequence_length, device=logits.device)).bool() + logits = logits.masked_fill(mask.unsqueeze(0), -1e4) + + return logits + + +class PPDocLayoutV2PositionRelationEmbedding(nn.Module): + inv_freq: torch.Tensor + + def __init__(self, config, device=None): + super().__init__() + self.config = config + self.embed_dim = config.relation_bias_embed_dim + self.scale = config.relation_bias_scale + self.pos_proj = nn.Conv2d( + in_channels=self.embed_dim * 4, out_channels=config.num_attention_heads, kernel_size=1 + ) + inv_freq, self.attention_scaling = self.compute_default_rope_parameters(config, device) + self.register_buffer("inv_freq", inv_freq, persistent=False) + + @staticmethod + def compute_default_rope_parameters( + config: PPDocLayoutV2Config | None = None, + device: Optional["torch.device"] = None, + seq_len: int | None = None, + ) -> tuple["torch.Tensor", float]: + """ + Computes the inverse frequencies according to the original RoPE implementation + Args: + config ([`~transformers.PreTrainedConfig`]): + The model configuration. + device (`torch.device`): + The device to use for initialization of the inverse frequencies. + seq_len (`int`, *optional*): + The current sequence length. Unused for this type of RoPE. + Returns: + Tuple of (`torch.Tensor`, `float`), containing the inverse frequencies for the RoPE embeddings and the + post-processing scaling factor applied to the computed cos/sin (unused in this type of RoPE). + """ + base = config.relation_bias_theta + dim = config.relation_bias_embed_dim + half_dim = dim // 2 + + attention_factor = 1.0 # Unused in this type of RoPE + + # Compute the inverse frequencies + inv_freq = 1.0 / ( + base ** (torch.arange(0, dim, 2, dtype=torch.int64).to(device=device, dtype=torch.float) / half_dim) + ) + return inv_freq, attention_factor + + def box_relative_encoding( + self, source_boxes: torch.Tensor, target_boxes: torch.Tensor = None, epsilon: float = 1e-5 + ): + source_boxes, target_boxes = source_boxes.unsqueeze(-2), target_boxes.unsqueeze(-3) + source_coordinates, source_dim = source_boxes[..., :2], source_boxes[..., 2:] + target_coordinates, target_dim = target_boxes[..., :2], target_boxes[..., 2:] + + coordinate_difference = torch.abs(source_coordinates - target_coordinates) + relative_coordinates = torch.log(coordinate_difference / (source_dim + epsilon) + 1.0) + relative_dim = torch.log((source_dim + epsilon) / (target_dim + epsilon)) + + relative_encoding = torch.cat([relative_coordinates, relative_dim], dim=-1) + + return relative_encoding + + def get_position_embedding(self, x: torch.Tensor, scale: float = 100.0): + embedding = (x * scale).unsqueeze(-1) * self.inv_freq + embedding = torch.cat((embedding.sin(), embedding.cos()), dim=-1).flatten(start_dim=-2).to(x.dtype) + + return embedding + + def forward(self, source_boxes: torch.Tensor, target_boxes: torch.Tensor = None): + if target_boxes is None: + target_boxes = source_boxes + with torch.no_grad(): + relative_encoding = self.box_relative_encoding(source_boxes, target_boxes) + position_embedding = self.get_position_embedding(relative_encoding, self.scale) + position_embedding = position_embedding.permute(0, 3, 1, 2) + out = self.pos_proj(position_embedding) + return out + + +class PPDocLayoutV2ReadingOrderSelfAttention(nn.Module): + def __init__(self, config): + super().__init__() + if config.hidden_size % config.num_attention_heads != 0 and not hasattr(config, "embedding_size"): + raise ValueError( + f"The hidden size ({config.hidden_size}) is not a multiple of the number of attention " + f"heads ({config.num_attention_heads})" + ) + + self.num_attention_heads = config.num_attention_heads + self.attention_head_size = int(config.hidden_size / config.num_attention_heads) + self.all_head_size = self.num_attention_heads * self.attention_head_size + + self.query = nn.Linear(config.hidden_size, self.all_head_size) + self.key = nn.Linear(config.hidden_size, self.all_head_size) + self.value = nn.Linear(config.hidden_size, self.all_head_size) + + self.dropout = nn.Dropout(config.attention_probs_dropout_prob) + self.has_relative_attention_bias = config.has_relative_attention_bias + self.has_spatial_attention_bias = config.has_spatial_attention_bias + + def cogview_attention(self, attention_scores, alpha=32): + """ + https://huggingface.co/papers/2105.13290 Section 2.4 Stabilization of training: Precision Bottleneck Relaxation + (PB-Relax). A replacement of the original nn.Softmax(dim=-1)(attention_scores). Seems the new attention_probs + will result in a slower speed and a little bias. Can use torch.allclose(standard_attention_probs, + cogview_attention_probs, atol=1e-08) for comparison. The smaller atol (e.g., 1e-08), the better. + """ + scaled_attention_scores = attention_scores / alpha + max_value = scaled_attention_scores.amax(dim=(-1)).unsqueeze(-1) + new_attention_scores = (scaled_attention_scores - max_value) * alpha + return nn.Softmax(dim=-1)(new_attention_scores) + + def forward( + self, + hidden_states, + attention_mask=None, + output_attentions=False, + rel_pos=None, + rel_2d_pos=None, + ): + batch_size, seq_length, _ = hidden_states.shape + query_layer = ( + self.query(hidden_states) + .view(batch_size, -1, self.num_attention_heads, self.attention_head_size) + .transpose(1, 2) + ) + key_layer = ( + self.key(hidden_states) + .view(batch_size, -1, self.num_attention_heads, self.attention_head_size) + .transpose(1, 2) + ) + value_layer = ( + self.value(hidden_states) + .view(batch_size, -1, self.num_attention_heads, self.attention_head_size) + .transpose(1, 2) + ) + + # Take the dot product between "query" and "key" to get the raw attention scores. + # The attention scores QT K/√d could be significantly larger than input elements, and result in overflow. + # Changing the computational order into QT(K/√d) alleviates the problem. (https://huggingface.co/papers/2105.13290) + attention_scores = torch.matmul(query_layer / math.sqrt(self.attention_head_size), key_layer.transpose(-1, -2)) + + # NOTE: + # PPDocLayoutV2ReadingOrder applies unscaled rel_2d_pos + # unlike LayoutLMv3 which uses (rel_pos + rel_2d_pos) / math.sqrt(self.attention_head_size) + if rel_2d_pos is not None: + attention_scores += rel_2d_pos + elif self.has_relative_attention_bias: + attention_scores += rel_pos / math.sqrt(self.attention_head_size) + + if attention_mask is not None: + # Apply the attention mask is (precomputed for all layers in RobertaModel forward() function) + attention_scores = attention_scores + attention_mask + + # Normalize the attention scores to probabilities. + # Use the trick of the CogView paper to stabilize training + attention_probs = self.cogview_attention(attention_scores) + + # This is actually dropping out entire tokens to attend to, which might + # seem a bit unusual, but is taken from the original Transformer paper. + attention_probs = self.dropout(attention_probs) + + context_layer = torch.matmul(attention_probs, value_layer) + + context_layer = context_layer.permute(0, 2, 1, 3).contiguous() + new_context_layer_shape = context_layer.size()[:-2] + (self.all_head_size,) + context_layer = context_layer.view(*new_context_layer_shape) + + outputs = (context_layer, attention_probs) if output_attentions else (context_layer,) + + return outputs + + +class PPDocLayoutV2ReadingOrderSelfOutput(nn.Module): + def __init__(self, config): + super().__init__() + self.dense = nn.Linear(config.hidden_size, config.hidden_size) + self.dropout = nn.Dropout(config.hidden_dropout_prob) + self.norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps) + + def forward(self, hidden_states: torch.Tensor, input_tensor: torch.Tensor) -> torch.Tensor: + hidden_states = self.dense(hidden_states) + hidden_states = self.dropout(hidden_states) + hidden_states = self.norm(hidden_states + input_tensor) + return hidden_states + + +class PPDocLayoutV2ReadingOrderIntermediate(nn.Module): + def __init__(self, config): + super().__init__() + self.dense = nn.Linear(config.hidden_size, config.intermediate_size) + if isinstance(config.hidden_act, str): + self.intermediate_act_fn = ACT2FN[config.hidden_act] + else: + self.intermediate_act_fn = config.hidden_act + + def forward(self, hidden_states: torch.Tensor) -> torch.Tensor: + hidden_states = self.dense(hidden_states) + hidden_states = self.intermediate_act_fn(hidden_states) + return hidden_states + + +class PPDocLayoutV2ReadingOrderOutput(nn.Module): + def __init__(self, config): + super().__init__() + self.dense = nn.Linear(config.intermediate_size, config.hidden_size) + self.dropout = nn.Dropout(config.hidden_dropout_prob) + self.norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps) + + def forward(self, hidden_states: torch.Tensor, input_tensor: torch.Tensor) -> torch.Tensor: + hidden_states = self.dense(hidden_states) + hidden_states = self.dropout(hidden_states) + hidden_states = self.norm(hidden_states + input_tensor) + return hidden_states + + +class PPDocLayoutV2ReadingOrderAttention(nn.Module): + def __init__(self, config): + super().__init__() + self.self = PPDocLayoutV2ReadingOrderSelfAttention(config) + self.output = PPDocLayoutV2ReadingOrderSelfOutput(config) + + def forward( + self, + hidden_states, + attention_mask=None, + output_attentions=False, + rel_pos=None, + rel_2d_pos=None, + ): + self_outputs = self.self( + hidden_states, + attention_mask, + output_attentions, + rel_pos=rel_pos, + rel_2d_pos=rel_2d_pos, + ) + attention_output = self.output(self_outputs[0], hidden_states) + outputs = (attention_output,) + self_outputs[1:] # add attentions if we output them + return outputs + + +class PPDocLayoutV2ReadingOrderLayer(GradientCheckpointingLayer): + def __init__(self, config): + super().__init__() + self.chunk_size_feed_forward = config.chunk_size_feed_forward + self.seq_len_dim = 1 + self.attention = PPDocLayoutV2ReadingOrderAttention(config) + self.intermediate = PPDocLayoutV2ReadingOrderIntermediate(config) + self.output = PPDocLayoutV2ReadingOrderOutput(config) + + def forward( + self, + hidden_states, + attention_mask=None, + output_attentions=False, + rel_pos=None, + rel_2d_pos=None, + ): + self_attention_outputs = self.attention( + hidden_states, + attention_mask, + output_attentions=output_attentions, + rel_pos=rel_pos, + rel_2d_pos=rel_2d_pos, + ) + attention_output = self_attention_outputs[0] + + outputs = self_attention_outputs[1:] # add self attentions if we output attention weights + + layer_output = apply_chunking_to_forward( + self.feed_forward_chunk, self.chunk_size_feed_forward, self.seq_len_dim, attention_output + ) + outputs = (layer_output,) + outputs + + return outputs + + def feed_forward_chunk(self, attention_output): + intermediate_output = self.intermediate(attention_output) + layer_output = self.output(intermediate_output, attention_output) + return layer_output + + +class PPDocLayoutV2ReadingOrderEncoder(nn.Module): + def __init__(self, config): + super().__init__() + self.config = config + self.layer = nn.ModuleList([PPDocLayoutV2ReadingOrderLayer(config) for _ in range(config.num_hidden_layers)]) + self.gradient_checkpointing = False + + self.has_relative_attention_bias = config.has_relative_attention_bias + self.has_spatial_attention_bias = config.has_spatial_attention_bias + + if self.has_relative_attention_bias: + self.rel_pos_bins = config.rel_pos_bins + self.max_rel_pos = config.max_rel_pos + self.rel_pos_bias = nn.Linear(self.rel_pos_bins, config.num_attention_heads, bias=False) + + if self.has_spatial_attention_bias: + self.max_rel_2d_pos = config.max_rel_2d_pos + self.rel_2d_pos_bins = config.rel_2d_pos_bins + self.rel_pos_x_bias = nn.Linear(self.rel_2d_pos_bins, config.num_attention_heads, bias=False) + self.rel_pos_y_bias = nn.Linear(self.rel_2d_pos_bins, config.num_attention_heads, bias=False) + self.rel_bias_module = PPDocLayoutV2PositionRelationEmbedding(config) + + def relative_position_bucket(self, relative_position, bidirectional=True, num_buckets=32, max_distance=128): + ret = 0 + if bidirectional: + num_buckets //= 2 + ret += (relative_position > 0).long() * num_buckets + n = torch.abs(relative_position) + else: + n = torch.max(-relative_position, torch.zeros_like(relative_position)) + # now n is in the range [0, inf) + + # half of the buckets are for exact increments in positions + max_exact = num_buckets // 2 + is_small = n < max_exact + + # The other half of the buckets are for logarithmically bigger bins in positions up to max_distance + val_if_large = max_exact + ( + torch.log(n.float() / max_exact) / math.log(max_distance / max_exact) * (num_buckets - max_exact) + ).to(torch.long) + val_if_large = torch.min(val_if_large, torch.full_like(val_if_large, num_buckets - 1)) + + ret += torch.where(is_small, n, val_if_large) + return ret + + def _cal_1d_pos_emb(self, position_ids): + rel_pos_mat = position_ids.unsqueeze(-2) - position_ids.unsqueeze(-1) + + rel_pos = self.relative_position_bucket( + rel_pos_mat, + num_buckets=self.rel_pos_bins, + max_distance=self.max_rel_pos, + ) + # Since this is a simple indexing operation that is independent of the input, + # no need to track gradients for this operation + # + # Without this no_grad context, training speed slows down significantly + with torch.no_grad(): + rel_pos = self.rel_pos_bias.weight.t()[rel_pos].permute(0, 3, 1, 2) + rel_pos = rel_pos.contiguous() + return rel_pos + + def _cal_2d_pos_emb(self, bbox): + x_min, y_min, x_max, y_max = ( + bbox[..., 0], + bbox[..., 1], + bbox[..., 2], + bbox[..., 3], + ) + + width = (x_max - x_min).clamp(min=1e-3) + height = (y_max - y_min).clamp(min=1e-3) + + center_x = (x_min + x_max) * 0.5 + center_y = (y_min + y_max) * 0.5 + + center_width_height_bbox = torch.stack([center_x, center_y, width, height], dim=-1) + + result = self.rel_bias_module(center_width_height_bbox) + + return result + + def forward( + self, + hidden_states, + bbox=None, + attention_mask=None, + output_attentions=False, + output_hidden_states=False, + return_dict=True, + position_ids=None, + patch_height=None, + patch_width=None, + ): + all_hidden_states = () if output_hidden_states else None + all_self_attentions = () if output_attentions else None + + rel_pos = self._cal_1d_pos_emb(position_ids) if self.has_relative_attention_bias else None + rel_2d_pos = self._cal_2d_pos_emb(bbox) if self.has_spatial_attention_bias else None + + for i, layer_module in enumerate(self.layer): + if output_hidden_states: + all_hidden_states = all_hidden_states + (hidden_states,) + + layer_outputs = layer_module( + hidden_states, + attention_mask, + output_attentions, + rel_pos=rel_pos, + rel_2d_pos=rel_2d_pos, + ) + + hidden_states = layer_outputs[0] + if output_attentions: + all_self_attentions = all_self_attentions + (layer_outputs[1],) + + if output_hidden_states: + all_hidden_states = all_hidden_states + (hidden_states,) + + if not return_dict: + return tuple( + v + for v in [ + hidden_states, + all_hidden_states, + all_self_attentions, + ] + if v is not None + ) + return BaseModelOutput( + last_hidden_state=hidden_states, + hidden_states=all_hidden_states, + attentions=all_self_attentions, + ) + + +class PPDocLayoutV2TextEmbeddings(nn.Module): + """ + PPDocLayoutV2 text embeddings. Same as `RobertaEmbeddings` but with added spatial (layout) embeddings. + """ + + def __init__(self, config): + super().__init__() + self.word_embeddings = nn.Embedding(config.vocab_size, config.hidden_size, padding_idx=config.pad_token_id) + self.token_type_embeddings = nn.Embedding(config.type_vocab_size, config.hidden_size) + self.dropout = nn.Dropout(config.hidden_dropout_prob) + + # position_ids (1, len position emb) is contiguous in memory and exported when serialized + self.register_buffer( + "position_ids", torch.arange(config.max_position_embeddings).expand((1, -1)), persistent=False + ) + + self.padding_idx = config.pad_token_id + self.position_embeddings = nn.Embedding( + config.max_position_embeddings, config.hidden_size, padding_idx=self.padding_idx + ) + + self.x_position_embeddings = nn.Embedding(config.max_2d_position_embeddings, config.coordinate_size) + self.y_position_embeddings = nn.Embedding(config.max_2d_position_embeddings, config.coordinate_size) + self.h_position_embeddings = nn.Embedding(config.max_2d_position_embeddings, config.shape_size) + self.w_position_embeddings = nn.Embedding(config.max_2d_position_embeddings, config.shape_size) + self.norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps) + spatial_embed_dim = 4 * config.coordinate_size + 2 * config.shape_size + self.spatial_proj = nn.Linear(spatial_embed_dim, config.hidden_size) + + def calculate_spatial_position_embeddings(self, bbox): + try: + left_position_embeddings = self.x_position_embeddings(bbox[:, :, 0]) + upper_position_embeddings = self.y_position_embeddings(bbox[:, :, 1]) + right_position_embeddings = self.x_position_embeddings(bbox[:, :, 2]) + lower_position_embeddings = self.y_position_embeddings(bbox[:, :, 3]) + except IndexError as e: + raise IndexError("The `bbox` coordinate values should be within 0-1000 range.") from e + + h_position_embeddings = self.h_position_embeddings(torch.clip(bbox[:, :, 3] - bbox[:, :, 1], 0, 1023)) + w_position_embeddings = self.w_position_embeddings(torch.clip(bbox[:, :, 2] - bbox[:, :, 0], 0, 1023)) + + # below is the difference between LayoutLMEmbeddingsV2 (torch.cat) and LayoutLMEmbeddingsV1 (add) + spatial_position_embeddings = torch.cat( + [ + left_position_embeddings, + upper_position_embeddings, + right_position_embeddings, + lower_position_embeddings, + h_position_embeddings, + w_position_embeddings, + ], + dim=-1, + ) + return spatial_position_embeddings + + def create_position_ids_from_input_ids(self, input_ids, padding_idx): + """ + Replace non-padding symbols with their position numbers. Position numbers begin at padding_idx+1. Padding + symbols are ignored. This is modified from fairseq's `utils.make_positions`. + """ + # The series of casts and type-conversions here are carefully balanced to both work with ONNX export and XLA. + mask = input_ids.ne(padding_idx).int() + incremental_indices = (torch.cumsum(mask, dim=1).type_as(mask)) * mask + return incremental_indices.long() + padding_idx + + def create_position_ids_from_inputs_embeds(self, inputs_embeds): + """ + We are provided embeddings directly. We cannot infer which are padded so just generate sequential position ids. + """ + input_shape = inputs_embeds.size()[:-1] + sequence_length = input_shape[1] + + position_ids = torch.arange( + self.padding_idx + 1, sequence_length + self.padding_idx + 1, dtype=torch.long, device=inputs_embeds.device + ) + return position_ids.unsqueeze(0).expand(input_shape) + + def forward( + self, + input_ids=None, + bbox=None, + token_type_ids=None, + position_ids=None, + inputs_embeds=None, + ): + if position_ids is None: + if input_ids is not None: + # Create the position ids from the input token ids. Any padded tokens remain padded. + position_ids = self.create_position_ids_from_input_ids(input_ids, self.padding_idx).to( + input_ids.device + ) + else: + position_ids = self.create_position_ids_from_inputs_embeds(inputs_embeds) + + if input_ids is not None: + input_shape = input_ids.size() + else: + input_shape = inputs_embeds.size()[:-1] + + if token_type_ids is None: + token_type_ids = torch.zeros(input_shape, dtype=torch.long, device=self.position_ids.device) + + if inputs_embeds is None: + inputs_embeds = self.word_embeddings(input_ids) + + token_type_embeddings = self.token_type_embeddings(token_type_ids) + embeddings = inputs_embeds + token_type_embeddings + + position_embeddings = self.position_embeddings(position_ids) + embeddings += position_embeddings + + # custom new spatial embeddings + spatial_position_embeddings = self.calculate_spatial_position_embeddings(bbox) + spatial_position_embeddings = self.spatial_proj(spatial_position_embeddings) + embeddings += spatial_position_embeddings + return embeddings + + +@use_kernel_forward_from_hub("MultiScaleDeformableAttention") +class MultiScaleDeformableAttention(nn.Module): + def forward( + self, + value: Tensor, + value_spatial_shapes: Tensor, + value_spatial_shapes_list: list[tuple], + level_start_index: Tensor, + sampling_locations: Tensor, + attention_weights: Tensor, + im2col_step: int, + ): + batch_size, _, num_heads, hidden_dim = value.shape + _, num_queries, num_heads, num_levels, num_points, _ = sampling_locations.shape + value_list = value.split([height * width for height, width in value_spatial_shapes_list], dim=1) + sampling_grids = 2 * sampling_locations - 1 + sampling_value_list = [] + for level_id, (height, width) in enumerate(value_spatial_shapes_list): + # batch_size, height*width, num_heads, hidden_dim + # -> batch_size, height*width, num_heads*hidden_dim + # -> batch_size, num_heads*hidden_dim, height*width + # -> batch_size*num_heads, hidden_dim, height, width + value_l_ = ( + value_list[level_id] + .flatten(2) + .transpose(1, 2) + .reshape(batch_size * num_heads, hidden_dim, height, width) + ) + # batch_size, num_queries, num_heads, num_points, 2 + # -> batch_size, num_heads, num_queries, num_points, 2 + # -> batch_size*num_heads, num_queries, num_points, 2 + sampling_grid_l_ = sampling_grids[:, :, :, level_id].transpose(1, 2).flatten(0, 1) + # batch_size*num_heads, hidden_dim, num_queries, num_points + sampling_value_l_ = nn.functional.grid_sample( + value_l_, + sampling_grid_l_, + mode="bilinear", + padding_mode="zeros", + align_corners=False, + ) + sampling_value_list.append(sampling_value_l_) + # (batch_size, num_queries, num_heads, num_levels, num_points) + # -> (batch_size, num_heads, num_queries, num_levels, num_points) + # -> (batch_size, num_heads, 1, num_queries, num_levels*num_points) + attention_weights = attention_weights.transpose(1, 2).reshape( + batch_size * num_heads, 1, num_queries, num_levels * num_points + ) + output = ( + (torch.stack(sampling_value_list, dim=-2).flatten(-2) * attention_weights) + .sum(-1) + .view(batch_size, num_heads * hidden_dim, num_queries) + ) + return output.transpose(1, 2).contiguous() + + +class PPDocLayoutV2MultiscaleDeformableAttention(nn.Module): + """ + Multiscale deformable attention as proposed in Deformable DETR. + """ + + def __init__(self, config: PPDocLayoutV2Config, num_heads: int, n_points: int): + super().__init__() + + self.attn = MultiScaleDeformableAttention() + + if config.d_model % num_heads != 0: + raise ValueError( + f"embed_dim (d_model) must be divisible by num_heads, but got {config.d_model} and {num_heads}" + ) + dim_per_head = config.d_model // num_heads + # check if dim_per_head is power of 2 + if not ((dim_per_head & (dim_per_head - 1) == 0) and dim_per_head != 0): + warnings.warn( + "You'd better set embed_dim (d_model) in PPDocLayoutV2MultiscaleDeformableAttention to make the" + " dimension of each attention head a power of 2 which is more efficient in the authors' CUDA" + " implementation." + ) + + self.im2col_step = 64 + + self.d_model = config.d_model + self.n_levels = config.num_feature_levels + self.n_heads = num_heads + self.n_points = n_points + + self.sampling_offsets = nn.Linear(config.d_model, num_heads * self.n_levels * n_points * 2) + self.attention_weights = nn.Linear(config.d_model, num_heads * self.n_levels * n_points) + self.value_proj = nn.Linear(config.d_model, config.d_model) + self.output_proj = nn.Linear(config.d_model, config.d_model) + + self.disable_custom_kernels = config.disable_custom_kernels + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.Tensor | None = None, + encoder_hidden_states=None, + encoder_attention_mask=None, + position_embeddings: torch.Tensor | None = None, + reference_points=None, + spatial_shapes=None, + spatial_shapes_list=None, + level_start_index=None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor, torch.Tensor]: + # add position embeddings to the hidden states before projecting to queries and keys + if position_embeddings is not None: + hidden_states = hidden_states + position_embeddings + + batch_size, num_queries, _ = hidden_states.shape + batch_size, sequence_length, _ = encoder_hidden_states.shape + total_elements = sum(height * width for height, width in spatial_shapes_list) + torch_compilable_check( + total_elements == sequence_length, + "Make sure to align the spatial shapes with the sequence length of the encoder hidden states", + ) + + value = self.value_proj(encoder_hidden_states) + if attention_mask is not None: + # we invert the attention_mask + value = value.masked_fill(~attention_mask[..., None], float(0)) + value = value.view(batch_size, sequence_length, self.n_heads, self.d_model // self.n_heads) + sampling_offsets = self.sampling_offsets(hidden_states).view( + batch_size, num_queries, self.n_heads, self.n_levels, self.n_points, 2 + ) + attention_weights = self.attention_weights(hidden_states).view( + batch_size, num_queries, self.n_heads, self.n_levels * self.n_points + ) + attention_weights = F.softmax(attention_weights, -1).view( + batch_size, num_queries, self.n_heads, self.n_levels, self.n_points + ) + # batch_size, num_queries, n_heads, n_levels, n_points, 2 + num_coordinates = reference_points.shape[-1] + if num_coordinates == 2: + offset_normalizer = torch.stack([spatial_shapes[..., 1], spatial_shapes[..., 0]], -1) + sampling_locations = ( + reference_points[:, :, None, :, None, :] + + sampling_offsets / offset_normalizer[None, None, None, :, None, :] + ) + elif num_coordinates == 4: + sampling_locations = ( + reference_points[:, :, None, :, None, :2] + + sampling_offsets / self.n_points * reference_points[:, :, None, :, None, 2:] * 0.5 + ) + else: + raise ValueError(f"Last dim of reference_points must be 2 or 4, but got {reference_points.shape[-1]}") + + output = self.attn( + value, + spatial_shapes, + spatial_shapes_list, + level_start_index, + sampling_locations, + attention_weights, + self.im2col_step, + ) + + output = self.output_proj(output) + + return output, attention_weights + + +@auto_docstring +class PPDocLayoutV2PreTrainedModel(PreTrainedModel): + config: PPDocLayoutV2Config + base_model_prefix = "pp_doclayout_v2" + main_input_name = "pixel_values" + input_modalities = ("image",) + _no_split_modules = [r"PPDocLayoutV2HybridEncoder", r"PPDocLayoutV2DecoderLayer"] + _supports_sdpa = True + _supports_flash_attn = True + _supports_attention_backend = True + _supports_flex_attn = True + + @torch.no_grad() + def _init_weights(self, module): + """Initialize the weights""" + if isinstance(module, PPDocLayoutV2ForObjectDetection): + if module.model.decoder.class_embed is not None: + for layer in module.model.decoder.class_embed: + prior_prob = self.config.initializer_bias_prior_prob or 1 / (self.config.num_labels + 1) + bias = float(-math.log((1 - prior_prob) / prior_prob)) + init.xavier_uniform_(layer.weight) + init.constant_(layer.bias, bias) + + if module.model.decoder.bbox_embed is not None: + for layer in module.model.decoder.bbox_embed: + init.constant_(layer.layers[-1].weight, 0) + init.constant_(layer.layers[-1].bias, 0) + + elif isinstance(module, PPDocLayoutV2MultiscaleDeformableAttention): + init.constant_(module.sampling_offsets.weight, 0.0) + default_dtype = torch.get_default_dtype() + thetas = torch.arange(module.n_heads, dtype=torch.int64).to(default_dtype) * ( + 2.0 * math.pi / module.n_heads + ) + grid_init = torch.stack([thetas.cos(), thetas.sin()], -1) + grid_init = ( + (grid_init / grid_init.abs().max(-1, keepdim=True)[0]) + .view(module.n_heads, 1, 1, 2) + .repeat(1, module.n_levels, module.n_points, 1) + ) + for i in range(module.n_points): + grid_init[:, :, i, :] *= i + 1 + + init.copy_(module.sampling_offsets.bias, grid_init.view(-1)) + init.constant_(module.attention_weights.weight, 0.0) + init.constant_(module.attention_weights.bias, 0.0) + init.xavier_uniform_(module.value_proj.weight) + init.constant_(module.value_proj.bias, 0.0) + init.xavier_uniform_(module.output_proj.weight) + init.constant_(module.output_proj.bias, 0.0) + + elif isinstance(module, PPDocLayoutV2Model): + prior_prob = self.config.initializer_bias_prior_prob or 1 / (self.config.num_labels + 1) + bias = float(-math.log((1 - prior_prob) / prior_prob)) + init.xavier_uniform_(module.enc_score_head.weight) + init.constant_(module.enc_score_head.bias, bias) + + elif isinstance(module, (nn.Linear, nn.Conv2d, nn.BatchNorm2d)): + init.normal_(module.weight, mean=0.0, std=self.config.initializer_range) + if module.bias is not None: + init.zeros_(module.bias) + if getattr(module, "running_mean", None) is not None: + init.zeros_(module.running_mean) + init.ones_(module.running_var) + init.zeros_(module.num_batches_tracked) + + elif isinstance(module, nn.LayerNorm): + init.ones_(module.weight) + init.zeros_(module.bias) + + if hasattr(module, "weight_embedding") and self.config.learn_initial_query: + init.xavier_uniform_(module.weight_embedding.weight) + if hasattr(module, "denoising_class_embed") and self.config.num_denoising > 0: + init.xavier_uniform_(module.denoising_class_embed.weight) + if isinstance(module, PPDocLayoutV2TextEmbeddings): + init.copy_(module.position_ids, torch.arange(module.position_ids.shape[-1]).expand((1, -1))) + if isinstance(module, nn.Embedding): + init.normal_(module.weight, mean=0.0, std=self.config.initializer_range) + if module.padding_idx is not None: + init.zeros_(module.weight.data[module.padding_idx]) + if isinstance(module, PPDocLayoutV2PositionRelationEmbedding): + inv_freq, _ = module.compute_default_rope_parameters(module.config, module.inv_freq.device) + module.register_buffer("inv_freq", inv_freq, persistent=False) + + +@auto_docstring( + custom_intro=""" + PP-DocLayoutV2 ReadingOrder Model. This model consists of an encoder and a GlobalPointer head. + It takes layout features as input and outputs logits representing the relative ordering relationships + between elements, which are used to determine the final reading sequence. + """ +) +class PPDocLayoutV2ReadingOrder(PPDocLayoutV2PreTrainedModel): + # Attention is based on LayoutLMv3 (no interface) + _supports_sdpa = False + _supports_flash_attn = False + _supports_attention_backend = False + _supports_flex_attn = False + + def __init__(self, config): + super().__init__(config) + self.embeddings = PPDocLayoutV2TextEmbeddings(config) + self.label_embeddings = nn.Embedding(config.num_classes, config.hidden_size) + self.label_features_projection = nn.Linear(config.hidden_size, config.hidden_size) + self.encoder = PPDocLayoutV2ReadingOrderEncoder(config) + self.relative_head = PPDocLayoutV2GlobalPointer(config) + self.config = config + + self.post_init() + + @auto_docstring + def forward(self, boxes, labels=None, mask=None, **kwargs: Unpack[TransformersKwargs]): + r""" + boxes (`torch.Tensor` of shape `(batch_size, sequence_length, 4)`): + Bounding box coordinates of the detected layout elements **in [0, 1000] scale**. + Format is `[x_min, y_min, x_max, y_max]`. + The tensor usually contains sorted valid boxes followed by zero-padding. + + labels (`torch.Tensor` of shape `(batch_size, sequence_length)`, *optional*): + The **remapped** class indices for each layout element. + These are not necessarily the raw detection class IDs, but indices mapped via + `config.class_order` (e.g., mapping text/title/figure to specific reading-order category IDs). + + mask (`torch.Tensor` of shape `(batch_size, sequence_length)`, *optional*): + Boolean or Binary mask indicating valid detected elements after threshold filtering. + - True: Valid layout element. + - False: Padding/Empty element. + Used to determine the sequence length (`num_pred`) for the pointer mechanism. + """ + device = mask.device + batch_size, seq_len = mask.shape + num_pred = mask.sum(dim=1) + + input_ids = torch.full( + (batch_size, seq_len + 2), self.config.pad_token_id, dtype=torch.long, device=boxes.device + ) + input_ids[:, 0] = self.config.start_token_id + + pred_col_idx = torch.arange(seq_len + 2, device=device).unsqueeze(0) + pred_mask = (pred_col_idx >= 1) & (pred_col_idx <= num_pred.unsqueeze(1)) + input_ids[pred_mask] = self.config.pred_token_id + end_col_indices = num_pred + 1 + input_ids[torch.arange(batch_size, device=device), end_col_indices] = self.config.end_token_id + + pad_box = torch.zeros(size=[boxes.shape[0], 1, boxes.shape[-1]], dtype=boxes.dtype, device=boxes.device) + pad_boxes = torch.cat([pad_box, boxes, pad_box], dim=1) + bbox_embedding = self.embeddings(input_ids=input_ids, bbox=pad_boxes.long()) + + if labels is not None: + label_embs = self.label_embeddings(labels) + label_proj = self.label_features_projection(label_embs) + pad = torch.zeros( + size=[label_proj.shape[0], 1, label_proj.shape[-1]], dtype=label_proj.dtype, device=labels.device + ) + label_proj = torch.cat([pad, label_proj, pad], dim=1) + else: + label_proj = torch.zeros_like(bbox_embedding) + + final_embeddings = bbox_embedding + label_proj + final_embeddings = self.embeddings.norm(final_embeddings) + final_embeddings = self.embeddings.dropout(final_embeddings) + + attention_mask = pred_col_idx < (num_pred + 2).unsqueeze(1) + attention_mask = create_bidirectional_mask( + config=self.config, + inputs_embeds=final_embeddings, + attention_mask=attention_mask, + ) + encoder_output = self.encoder(hidden_states=final_embeddings, bbox=pad_boxes, attention_mask=attention_mask) + encoder_output = encoder_output.last_hidden_state + token = encoder_output[:, 1 : 1 + seq_len, :] + read_order_logits = self.relative_head(token) + return read_order_logits + + +@dataclass +@auto_docstring +class PPDocLayoutV2ForObjectDetectionOutput(ModelOutput): + r""" + logits (`torch.FloatTensor` of shape `(batch_size, num_queries, num_classes + 1)`): + Classification logits (including no-object) for all queries. + order_logits (`tuple` of `torch.FloatTensor` of shape `(batch_size, num_queries, num_queries)`): + Order logits for all queries. The first dimension of each tensor is the batch size. The second dimension is the number of queries. + pred_boxes (`torch.FloatTensor` of shape `(batch_size, num_queries, 4)`): + Normalized boxes coordinates for all queries, represented as (center_x, center_y, width, height). These + values are normalized in [0, 1], relative to the size of each individual image in the batch (disregarding + possible padding). You can use [`~RTDetrImageProcessor.post_process_object_detection`] to retrieve the + unnormalized (absolute) bounding boxes. + last_hidden_state (`torch.FloatTensor` of shape `(batch_size, num_queries, hidden_size)`): + Sequence of hidden-states at the output of the last layer of the decoder of the model. + intermediate_hidden_states (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, hidden_size)`): + Stacked intermediate hidden states (output of each layer of the decoder). + intermediate_logits (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, config.num_labels)`): + Stacked intermediate logits (logits of each layer of the decoder). + intermediate_reference_points (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, 4)`): + Stacked intermediate reference points (reference points of each layer of the decoder). + intermediate_predicted_corners (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, 4)`): + Stacked intermediate predicted corners (predicted corners of each layer of the decoder). + initial_reference_points (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, 4)`): + Stacked initial reference points (initial reference points of each layer of the decoder). + init_reference_points (`torch.FloatTensor` of shape `(batch_size, num_queries, 4)`): + Initial reference points sent through the Transformer decoder. + enc_topk_logits (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.num_labels)`, *optional*, returned when `config.with_box_refine=True` and `config.two_stage=True`): + Logits of predicted bounding boxes coordinates in the encoder. + enc_topk_bboxes (`torch.FloatTensor` of shape `(batch_size, sequence_length, 4)`, *optional*, returned when `config.with_box_refine=True` and `config.two_stage=True`): + Logits of predicted bounding boxes coordinates in the encoder. + enc_outputs_class (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.num_labels)`, *optional*, returned when `config.with_box_refine=True` and `config.two_stage=True`): + Predicted bounding boxes scores where the top `config.two_stage_num_proposals` scoring bounding boxes are + picked as region proposals in the first stage. Output of bounding box binary classification (i.e. + foreground and background). + enc_outputs_coord_logits (`torch.FloatTensor` of shape `(batch_size, sequence_length, 4)`, *optional*, returned when `config.with_box_refine=True` and `config.two_stage=True`): + Logits of predicted bounding boxes coordinates in the first stage. + denoising_meta_values (`dict`): + Extra dictionary for the denoising related values + """ + + logits: torch.FloatTensor | None = None + pred_boxes: torch.FloatTensor | None = None + order_logits: tuple[torch.FloatTensor] | None = None + last_hidden_state: torch.FloatTensor | None = None + intermediate_hidden_states: torch.FloatTensor | None = None + intermediate_logits: torch.FloatTensor | None = None + intermediate_reference_points: torch.FloatTensor | None = None + intermediate_predicted_corners: torch.FloatTensor | None = None + initial_reference_points: torch.FloatTensor | None = None + decoder_hidden_states: tuple[torch.FloatTensor] | None = None + decoder_attentions: tuple[torch.FloatTensor] | None = None + cross_attentions: tuple[torch.FloatTensor] | None = None + encoder_last_hidden_state: torch.FloatTensor | None = None + encoder_hidden_states: tuple[torch.FloatTensor] | None = None + encoder_attentions: tuple[torch.FloatTensor] | None = None + init_reference_points: tuple[torch.FloatTensor] | None = None + enc_topk_logits: torch.FloatTensor | None = None + enc_topk_bboxes: torch.FloatTensor | None = None + enc_outputs_class: torch.FloatTensor | None = None + enc_outputs_coord_logits: torch.FloatTensor | None = None + denoising_meta_values: dict | None = None + + +@dataclass +@auto_docstring( + custom_intro=""" + Base class for outputs of the PP-DocLayoutV2 encoder-decoder model. + """ +) +class PPDocLayoutV2ModelOutput(ModelOutput): + r""" + last_hidden_state (`torch.FloatTensor` of shape `(batch_size, num_queries, hidden_size)`): + Sequence of hidden-states at the output of the last layer of the decoder of the model. + intermediate_hidden_states (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, hidden_size)`): + Stacked intermediate hidden states (output of each layer of the decoder). + intermediate_logits (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, sequence_length, config.num_labels)`): + Stacked intermediate logits (logits of each layer of the decoder). + intermediate_reference_points (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, 4)`): + Stacked intermediate reference points (reference points of each layer of the decoder). + intermediate_predicted_corners (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, 4)`): + Stacked intermediate predicted corners (predicted corners of each layer of the decoder). + initial_reference_points (`torch.FloatTensor` of shape `(batch_size, num_queries, 4)`): + Initial reference points used for the first decoder layer. + init_reference_points (`torch.FloatTensor` of shape `(batch_size, num_queries, 4)`): + Initial reference points sent through the Transformer decoder. + enc_topk_logits (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.num_labels)`): + Predicted bounding boxes scores where the top `config.two_stage_num_proposals` scoring bounding boxes are + picked as region proposals in the encoder stage. Output of bounding box binary classification (i.e. + foreground and background). + enc_topk_bboxes (`torch.FloatTensor` of shape `(batch_size, sequence_length, 4)`): + Logits of predicted bounding boxes coordinates in the encoder stage. + enc_outputs_class (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.num_labels)`, *optional*, returned when `config.with_box_refine=True` and `config.two_stage=True`): + Predicted bounding boxes scores where the top `config.two_stage_num_proposals` scoring bounding boxes are + picked as region proposals in the first stage. Output of bounding box binary classification (i.e. + foreground and background). + enc_outputs_coord_logits (`torch.FloatTensor` of shape `(batch_size, sequence_length, 4)`, *optional*, returned when `config.with_box_refine=True` and `config.two_stage=True`): + Logits of predicted bounding boxes coordinates in the first stage. + denoising_meta_values (`dict`): + Extra dictionary for the denoising related values. + """ + + last_hidden_state: torch.FloatTensor | None = None + intermediate_hidden_states: torch.FloatTensor | None = None + intermediate_logits: torch.FloatTensor | None = None + intermediate_reference_points: torch.FloatTensor | None = None + intermediate_predicted_corners: torch.FloatTensor | None = None + initial_reference_points: torch.FloatTensor | None = None + decoder_hidden_states: tuple[torch.FloatTensor] | None = None + decoder_attentions: tuple[torch.FloatTensor] | None = None + cross_attentions: tuple[torch.FloatTensor] | None = None + encoder_last_hidden_state: torch.FloatTensor | None = None + encoder_hidden_states: tuple[torch.FloatTensor] | None = None + encoder_attentions: tuple[torch.FloatTensor] | None = None + init_reference_points: torch.FloatTensor | None = None + enc_topk_logits: torch.FloatTensor | None = None + enc_topk_bboxes: torch.FloatTensor | None = None + enc_outputs_class: torch.FloatTensor | None = None + enc_outputs_coord_logits: torch.FloatTensor | None = None + denoising_meta_values: dict | None = None + + +class PPDocLayoutV2MLPPredictionHead(nn.Module): + """ + Very simple multi-layer perceptron (MLP, also called FFN), used to predict the normalized center coordinates, + height and width of a bounding box w.r.t. an image. + + """ + + def __init__(self, input_dim, hidden_dim, output_dim, num_layers): + super().__init__() + self.num_layers = num_layers + h = [hidden_dim] * (num_layers - 1) + self.layers = nn.ModuleList(nn.Linear(n, k) for n, k in zip([input_dim] + h, h + [output_dim])) + + def forward(self, x): + for i, layer in enumerate(self.layers): + x = nn.functional.relu(layer(x)) if i < self.num_layers - 1 else layer(x) + return x + + +@dataclass +@auto_docstring( + custom_intro=""" + Base class for outputs of the PPDocLayoutV2Decoder. This class adds two attributes to + BaseModelOutputWithCrossAttentions, namely: + - a stacked tensor of intermediate decoder hidden states (i.e. the output of each decoder layer) + - a stacked tensor of intermediate reference points. + """ +) +class PPDocLayoutV2DecoderOutput(ModelOutput): + r""" + intermediate_hidden_states (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, hidden_size)`): + Stacked intermediate hidden states (output of each layer of the decoder). + intermediate_logits (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, sequence_length, config.num_labels)`): + Stacked intermediate logits (logits of each layer of the decoder). + intermediate_reference_points (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, sequence_length, hidden_size)`): + Stacked intermediate reference points (reference points of each layer of the decoder). + intermediate_predicted_corners (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, 4)`): + Stacked intermediate predicted corners (predicted corners of each layer of the decoder). + initial_reference_points (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, 4)`): + Stacked initial reference points (initial reference points of each layer of the decoder). + cross_attentions (`tuple(torch.FloatTensor)`, *optional*, returned when `output_attentions=True` and `config.add_cross_attention=True` is passed or when `config.output_attentions=True`): + Tuple of `torch.FloatTensor` (one for each layer) of shape `(batch_size, num_heads, sequence_length, + sequence_length)`. Attentions weights of the decoder's cross-attention layer, after the attention softmax, + used to compute the weighted average in the cross-attention heads. + """ + + last_hidden_state: torch.FloatTensor | None = None + intermediate_hidden_states: torch.FloatTensor | None = None + intermediate_logits: torch.FloatTensor | None = None + intermediate_reference_points: torch.FloatTensor | None = None + intermediate_predicted_corners: torch.FloatTensor | None = None + initial_reference_points: torch.FloatTensor | None = None + hidden_states: tuple[torch.FloatTensor] | None = None + attentions: tuple[torch.FloatTensor] | None = None + cross_attentions: tuple[torch.FloatTensor] | None = None + + +class PPDocLayoutV2MLP(nn.Module): + def __init__( + self, config: PPDocLayoutV2Config, hidden_size: int, intermediate_size: int, activation_function: str + ): + super().__init__() + self.fc1 = nn.Linear(hidden_size, intermediate_size) + self.fc2 = nn.Linear(intermediate_size, hidden_size) + self.activation_fn = ACT2FN[activation_function] + self.activation_dropout = config.activation_dropout + self.dropout = config.dropout + + def forward(self, hidden_states: torch.Tensor) -> torch.Tensor: + hidden_states = self.activation_fn(self.fc1(hidden_states)) + hidden_states = nn.functional.dropout(hidden_states, p=self.activation_dropout, training=self.training) + hidden_states = self.fc2(hidden_states) + hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training) + return hidden_states + + +class PPDocLayoutV2FrozenBatchNorm2d(nn.Module): + """ + BatchNorm2d where the batch statistics and the affine parameters are fixed. + + Copy-paste from torchvision.misc.ops with added eps before rqsrt, without which any other models than + torchvision.models.resnet[18,34,50,101] produce nans. + """ + + def __init__(self, n): + super().__init__() + self.register_buffer("weight", torch.ones(n)) + self.register_buffer("bias", torch.zeros(n)) + self.register_buffer("running_mean", torch.zeros(n)) + self.register_buffer("running_var", torch.ones(n)) + + def _load_from_state_dict( + self, state_dict, prefix, local_metadata, strict, missing_keys, unexpected_keys, error_msgs + ): + num_batches_tracked_key = prefix + "num_batches_tracked" + if num_batches_tracked_key in state_dict: + del state_dict[num_batches_tracked_key] + + super()._load_from_state_dict( + state_dict, prefix, local_metadata, strict, missing_keys, unexpected_keys, error_msgs + ) + + def forward(self, x): + # move reshapes to the beginning + # to make it user-friendly + weight = self.weight.reshape(1, -1, 1, 1) + bias = self.bias.reshape(1, -1, 1, 1) + running_var = self.running_var.reshape(1, -1, 1, 1) + running_mean = self.running_mean.reshape(1, -1, 1, 1) + epsilon = 1e-5 + scale = weight * (running_var + epsilon).rsqrt() + bias = bias - running_mean * scale + return x * scale + bias + + +def eager_attention_forward( + module: nn.Module, + query: torch.Tensor, + key: torch.Tensor, + value: torch.Tensor, + attention_mask: torch.Tensor | None, + scaling: float | None = None, + dropout: float = 0.0, + **kwargs: Unpack[TransformersKwargs], +): + if scaling is None: + scaling = query.size(-1) ** -0.5 + + # Take the dot product between "query" and "key" to get the raw attention scores. + attn_weights = torch.matmul(query, key.transpose(2, 3)) * scaling + + if attention_mask is not None: + attn_weights = attn_weights + attention_mask + + attn_weights = nn.functional.softmax(attn_weights, dim=-1) + attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training) + + attn_output = torch.matmul(attn_weights, value) + attn_output = attn_output.transpose(1, 2).contiguous() + + return attn_output, attn_weights + + +class PPDocLayoutV2SelfAttention(nn.Module): + """ + Multi-headed self-attention from 'Attention Is All You Need' paper. + + In PP_DOCLAYOUT_V2, position embeddings are added to both queries and keys (but not values) in self-attention. + """ + + def __init__( + self, + config: PPDocLayoutV2Config, + hidden_size: int, + num_attention_heads: int, + dropout: float = 0.0, + bias: bool = True, + ): + super().__init__() + self.config = config + self.head_dim = hidden_size // num_attention_heads + self.scaling = self.head_dim**-0.5 + self.attention_dropout = dropout + self.is_causal = False + + self.k_proj = nn.Linear(hidden_size, hidden_size, bias=bias) + self.v_proj = nn.Linear(hidden_size, hidden_size, bias=bias) + self.q_proj = nn.Linear(hidden_size, hidden_size, bias=bias) + self.o_proj = nn.Linear(hidden_size, hidden_size, bias=bias) + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.Tensor | None = None, + position_embeddings: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor, torch.Tensor]: + """ + Position embeddings are added to both queries and keys (but not values). + """ + input_shape = hidden_states.shape[:-1] + hidden_shape = (*input_shape, -1, self.head_dim) + + query_key_input = hidden_states + position_embeddings if position_embeddings is not None else hidden_states + + query_states = self.q_proj(query_key_input).view(hidden_shape).transpose(1, 2) + key_states = self.k_proj(query_key_input).view(hidden_shape).transpose(1, 2) + value_states = self.v_proj(hidden_states).view(hidden_shape).transpose(1, 2) + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, eager_attention_forward + ) + + attn_output, attn_weights = attention_interface( + self, + query_states, + key_states, + value_states, + attention_mask, + dropout=0.0 if not self.training else self.attention_dropout, + scaling=self.scaling, + **kwargs, + ) + + attn_output = attn_output.reshape(*input_shape, -1).contiguous() + attn_output = self.o_proj(attn_output) + return attn_output, attn_weights + + +def replace_batch_norm(model): + r""" + Recursively replace all `torch.nn.BatchNorm2d` with `PPDocLayoutV2FrozenBatchNorm2d`. + + Args: + model (torch.nn.Module): + input model + """ + for name, module in model.named_children(): + if isinstance(module, nn.BatchNorm2d): + new_module = PPDocLayoutV2FrozenBatchNorm2d(module.num_features) + + if module.weight.device != torch.device("meta"): + new_module.weight.copy_(module.weight) + new_module.bias.copy_(module.bias) + new_module.running_mean.copy_(module.running_mean) + new_module.running_var.copy_(module.running_var) + + model._modules[name] = new_module + + if len(list(module.children())) > 0: + replace_batch_norm(module) + + +class PPDocLayoutV2ConvEncoder(nn.Module): + """ + Convolutional backbone using the modeling_pp_doclayout_v2_resnet.py. + + nn.BatchNorm2d layers are replaced by PPDocLayoutV2FrozenBatchNorm2d as defined above. + https://github.com/lyuwenyu/RT-DETR/blob/main/PPDocLayoutV2_pytorch/src/nn/backbone/presnet.py#L142 + """ + + def __init__(self, config): + super().__init__() + + backbone = load_backbone(config) + + if config.freeze_backbone_batch_norms: + # replace batch norm by frozen batch norm + with torch.no_grad(): + replace_batch_norm(backbone) + self.model = backbone + self.intermediate_channel_sizes = self.model.channels + + def forward(self, pixel_values: torch.Tensor, pixel_mask: torch.Tensor): + # send pixel_values through the model to get list of feature maps + features = self.model(pixel_values).feature_maps + + out = [] + for feature_map in features: + # downsample pixel_mask to match shape of corresponding feature_map + mask = nn.functional.interpolate(pixel_mask[None].float(), size=feature_map.shape[-2:]).to(torch.bool)[0] + out.append((feature_map, mask)) + return out + + +class PPDocLayoutV2ConvNormLayer(nn.Module): + def __init__(self, config, in_channels, out_channels, kernel_size, stride, padding=None, activation=None): + super().__init__() + self.conv = nn.Conv2d( + in_channels, + out_channels, + kernel_size, + stride, + padding=(kernel_size - 1) // 2 if padding is None else padding, + bias=False, + ) + self.norm = nn.BatchNorm2d(out_channels, config.batch_norm_eps) + self.activation = nn.Identity() if activation is None else ACT2CLS[activation]() + + def forward(self, hidden_state): + hidden_state = self.conv(hidden_state) + hidden_state = self.norm(hidden_state) + hidden_state = self.activation(hidden_state) + return hidden_state + + +class PPDocLayoutV2EncoderLayer(nn.Module): + def __init__(self, config: PPDocLayoutV2Config): + super().__init__() + self.normalize_before = config.normalize_before + self.hidden_size = config.encoder_hidden_dim + + # self-attention + self.self_attn = PPDocLayoutV2SelfAttention( + config=config, + hidden_size=self.hidden_size, + num_attention_heads=config.num_attention_heads, + dropout=config.dropout, + ) + self.self_attn_layer_norm = nn.LayerNorm(self.hidden_size, eps=config.layer_norm_eps) + self.dropout = config.dropout + self.mlp = PPDocLayoutV2MLP( + config, self.hidden_size, config.encoder_ffn_dim, config.encoder_activation_function + ) + self.final_layer_norm = nn.LayerNorm(self.hidden_size, eps=config.layer_norm_eps) + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.Tensor, + spatial_position_embeddings: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> torch.Tensor: + """ + Args: + hidden_states (`torch.FloatTensor`): input to the layer of shape `(batch, seq_len, hidden_size)` + attention_mask (`torch.FloatTensor`): attention mask of size + `(batch, 1, target_len, source_len)` where padding elements are indicated by very large negative + values. + spatial_position_embeddings (`torch.FloatTensor`, *optional*): + Spatial position embeddings (2D positional encodings of image locations), to be added to both + the queries and keys in self-attention (but not to values). + """ + residual = hidden_states + if self.normalize_before: + hidden_states = self.self_attn_layer_norm(hidden_states) + + hidden_states, _ = self.self_attn( + hidden_states=hidden_states, + attention_mask=attention_mask, + position_embeddings=spatial_position_embeddings, + **kwargs, + ) + + hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training) + hidden_states = residual + hidden_states + if not self.normalize_before: + hidden_states = self.self_attn_layer_norm(hidden_states) + + if self.normalize_before: + hidden_states = self.final_layer_norm(hidden_states) + residual = hidden_states + + hidden_states = self.mlp(hidden_states) + + hidden_states = residual + hidden_states + if not self.normalize_before: + hidden_states = self.final_layer_norm(hidden_states) + + if self.training: + if not torch.isfinite(hidden_states).all(): + clamp_value = torch.finfo(hidden_states.dtype).max - 1000 + hidden_states = torch.clamp(hidden_states, min=-clamp_value, max=clamp_value) + + return hidden_states + + +class PPDocLayoutV2RepVggBlock(nn.Module): + """ + RepVGG architecture block introduced by the work "RepVGG: Making VGG-style ConvNets Great Again". + """ + + def __init__(self, config: PPDocLayoutV2Config): + super().__init__() + + activation = config.activation_function + hidden_channels = int(config.encoder_hidden_dim * config.hidden_expansion) + self.conv1 = PPDocLayoutV2ConvNormLayer(config, hidden_channels, hidden_channels, 3, 1, padding=1) + self.conv2 = PPDocLayoutV2ConvNormLayer(config, hidden_channels, hidden_channels, 1, 1, padding=0) + self.activation = nn.Identity() if activation is None else ACT2CLS[activation]() + + def forward(self, x): + y = self.conv1(x) + self.conv2(x) + return self.activation(y) + + +class PPDocLayoutV2CSPRepLayer(nn.Module): + """ + Cross Stage Partial (CSP) network layer with RepVGG blocks. + """ + + def __init__(self, config: PPDocLayoutV2Config): + super().__init__() + + in_channels = config.encoder_hidden_dim * 2 + out_channels = config.encoder_hidden_dim + num_blocks = 3 + activation = config.activation_function + + hidden_channels = int(out_channels * config.hidden_expansion) + self.conv1 = PPDocLayoutV2ConvNormLayer(config, in_channels, hidden_channels, 1, 1, activation=activation) + self.conv2 = PPDocLayoutV2ConvNormLayer(config, in_channels, hidden_channels, 1, 1, activation=activation) + self.bottlenecks = nn.Sequential(*[PPDocLayoutV2RepVggBlock(config) for _ in range(num_blocks)]) + if hidden_channels != out_channels: + self.conv3 = PPDocLayoutV2ConvNormLayer(config, hidden_channels, out_channels, 1, 1, activation=activation) + else: + self.conv3 = nn.Identity() + + def forward(self, hidden_state): + hidden_state_1 = self.conv1(hidden_state) + hidden_state_1 = self.bottlenecks(hidden_state_1) + hidden_state_2 = self.conv2(hidden_state) + return self.conv3(hidden_state_1 + hidden_state_2) + + +class PPDocLayoutV2DecoderLayer(nn.Module): + def __init__(self, config: PPDocLayoutV2Config): + super().__init__() + self.hidden_size = config.d_model + + # self-attention + self.self_attn = PPDocLayoutV2SelfAttention( + config=config, + hidden_size=self.hidden_size, + num_attention_heads=config.decoder_attention_heads, + dropout=config.attention_dropout, + ) + self.dropout = config.dropout + + self.self_attn_layer_norm = nn.LayerNorm(self.hidden_size, eps=config.layer_norm_eps) + # cross-attention + self.encoder_attn = PPDocLayoutV2MultiscaleDeformableAttention( + config, + num_heads=config.decoder_attention_heads, + n_points=config.decoder_n_points, + ) + self.encoder_attn_layer_norm = nn.LayerNorm(self.hidden_size, eps=config.layer_norm_eps) + # feedforward neural networks + self.mlp = PPDocLayoutV2MLP( + config, self.hidden_size, config.decoder_ffn_dim, config.decoder_activation_function + ) + self.final_layer_norm = nn.LayerNorm(self.hidden_size, eps=config.layer_norm_eps) + + def forward( + self, + hidden_states: torch.Tensor, + object_queries_position_embeddings: torch.Tensor | None = None, + reference_points=None, + spatial_shapes=None, + spatial_shapes_list=None, + level_start_index=None, + encoder_hidden_states: torch.Tensor | None = None, + encoder_attention_mask: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> torch.Tensor: + """ + Args: + hidden_states (`torch.FloatTensor`): + Input to the layer of shape `(batch, seq_len, hidden_size)`. + object_queries_position_embeddings (`torch.FloatTensor`, *optional*): + Position embeddings for the object query slots. These are added to both queries and keys + in the self-attention layer (not values). + reference_points (`torch.FloatTensor`, *optional*): + Reference points. + spatial_shapes (`torch.LongTensor`, *optional*): + Spatial shapes. + level_start_index (`torch.LongTensor`, *optional*): + Level start index. + encoder_hidden_states (`torch.FloatTensor`): + cross attention input to the layer of shape `(batch, seq_len, hidden_size)` + encoder_attention_mask (`torch.FloatTensor`): encoder attention mask of size + `(batch, 1, target_len, source_len)` where padding elements are indicated by very large negative + values. + """ + residual = hidden_states + + # Self Attention + hidden_states, _ = self.self_attn( + hidden_states=hidden_states, + attention_mask=encoder_attention_mask, + position_embeddings=object_queries_position_embeddings, + **kwargs, + ) + + hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training) + hidden_states = residual + hidden_states + hidden_states = self.self_attn_layer_norm(hidden_states) + + residual = hidden_states + + # Cross-Attention + hidden_states, _ = self.encoder_attn( + hidden_states=hidden_states, + encoder_hidden_states=encoder_hidden_states, + position_embeddings=object_queries_position_embeddings, + reference_points=reference_points, + spatial_shapes=spatial_shapes, + spatial_shapes_list=spatial_shapes_list, + level_start_index=level_start_index, + **kwargs, + ) + + hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training) + hidden_states = residual + hidden_states + + hidden_states = self.encoder_attn_layer_norm(hidden_states) + + # Fully Connected + residual = hidden_states + hidden_states = self.mlp(hidden_states) + hidden_states = residual + hidden_states + hidden_states = self.final_layer_norm(hidden_states) + + return hidden_states + + +class PPDocLayoutV2SinePositionEmbedding(nn.Module): + """ + 2D sinusoidal position embedding used in RT-DETR hybrid encoder. + """ + + def __init__(self, embed_dim: int = 256, temperature: int = 10000): + super().__init__() + self.embed_dim = embed_dim + self.temperature = temperature + + @compile_compatible_method_lru_cache(maxsize=32) + def forward( + self, + width: int, + height: int, + device: torch.device | str, + dtype: torch.dtype, + ) -> torch.Tensor: + """ + Generate 2D sinusoidal position embeddings. + + Returns: + Position embeddings of shape (1, height*width, embed_dim) + """ + grid_w = torch.arange(torch_int(width), device=device).to(dtype) + grid_h = torch.arange(torch_int(height), device=device).to(dtype) + grid_w, grid_h = torch.meshgrid(grid_w, grid_h, indexing="xy") + if self.embed_dim % 4 != 0: + raise ValueError("Embed dimension must be divisible by 4 for 2D sin-cos position embedding") + pos_dim = self.embed_dim // 4 + omega = torch.arange(pos_dim, device=device).to(dtype) / pos_dim + omega = 1.0 / (self.temperature**omega) + + out_w = grid_w.flatten()[..., None] @ omega[None] + out_h = grid_h.flatten()[..., None] @ omega[None] + + return torch.concat([out_h.sin(), out_h.cos(), out_w.sin(), out_w.cos()], dim=1)[None, :, :] + + +class PPDocLayoutV2AIFILayer(nn.Module): + """ + AIFI (Attention-based Intra-scale Feature Interaction) layer used in RT-DETR hybrid encoder. + """ + + def __init__(self, config: PPDocLayoutV2Config): + super().__init__() + self.config = config + self.encoder_hidden_dim = config.encoder_hidden_dim + self.eval_size = config.eval_size + + self.position_embedding = PPDocLayoutV2SinePositionEmbedding( + embed_dim=self.encoder_hidden_dim, + temperature=config.positional_encoding_temperature, + ) + self.layers = nn.ModuleList([PPDocLayoutV2EncoderLayer(config) for _ in range(config.encoder_layers)]) + + def forward( + self, + hidden_states: torch.Tensor, + **kwargs: Unpack[TransformersKwargs], + ) -> torch.Tensor: + """ + Args: + hidden_states (`torch.FloatTensor` of shape `(batch_size, channels, height, width)`): + Feature map to process. + """ + batch_size = hidden_states.shape[0] + height, width = hidden_states.shape[2:] + + hidden_states = hidden_states.flatten(2).permute(0, 2, 1) + + if self.training or self.eval_size is None: + pos_embed = self.position_embedding( + width=width, + height=height, + device=hidden_states.device, + dtype=hidden_states.dtype, + ) + else: + pos_embed = None + + for layer in self.layers: + hidden_states = layer( + hidden_states, + attention_mask=None, + spatial_position_embeddings=pos_embed, + **kwargs, + ) + + hidden_states = ( + hidden_states.permute(0, 2, 1).reshape(batch_size, self.encoder_hidden_dim, height, width).contiguous() + ) + + return hidden_states + + +class PPDocLayoutV2HybridEncoder(PPDocLayoutV2PreTrainedModel): + """ + Hybrid encoder consisting of AIFI (Attention-based Intra-scale Feature Interaction) layers, + a top-down Feature Pyramid Network (FPN) and a bottom-up Path Aggregation Network (PAN). + More details on the paper: https://huggingface.co/papers/2304.08069 + + Args: + config: PPDocLayoutV2Config + """ + + _can_record_outputs = { + "hidden_states": PPDocLayoutV2AIFILayer, + "attentions": PPDocLayoutV2SelfAttention, + } + + def __init__(self, config: PPDocLayoutV2Config): + super().__init__(config) + self.config = config + self.in_channels = config.encoder_in_channels + self.feat_strides = config.feat_strides + self.encoder_hidden_dim = config.encoder_hidden_dim + self.encode_proj_layers = config.encode_proj_layers + self.positional_encoding_temperature = config.positional_encoding_temperature + self.eval_size = config.eval_size + self.out_channels = [self.encoder_hidden_dim for _ in self.in_channels] + self.out_strides = self.feat_strides + self.num_fpn_stages = len(self.in_channels) - 1 + self.num_pan_stages = len(self.in_channels) - 1 + + # AIFI (Attention-based Intra-scale Feature Interaction) layers + self.aifi = nn.ModuleList([PPDocLayoutV2AIFILayer(config) for _ in range(len(self.encode_proj_layers))]) + + # top-down FPN + self.lateral_convs = nn.ModuleList() + self.fpn_blocks = nn.ModuleList() + for _ in range(self.num_fpn_stages): + lateral_conv = PPDocLayoutV2ConvNormLayer( + config, + in_channels=self.encoder_hidden_dim, + out_channels=self.encoder_hidden_dim, + kernel_size=1, + stride=1, + activation=config.activation_function, + ) + fpn_block = PPDocLayoutV2CSPRepLayer(config) + self.lateral_convs.append(lateral_conv) + self.fpn_blocks.append(fpn_block) + + # bottom-up PAN + self.downsample_convs = nn.ModuleList() + self.pan_blocks = nn.ModuleList() + for _ in range(self.num_pan_stages): + downsample_conv = PPDocLayoutV2ConvNormLayer( + config, + in_channels=self.encoder_hidden_dim, + out_channels=self.encoder_hidden_dim, + kernel_size=3, + stride=2, + activation=config.activation_function, + ) + pan_block = PPDocLayoutV2CSPRepLayer(config) + self.downsample_convs.append(downsample_conv) + self.pan_blocks.append(pan_block) + + self.post_init() + + @merge_with_config_defaults + @capture_outputs(tie_last_hidden_states=False) + def forward( + self, + inputs_embeds=None, + **kwargs: Unpack[TransformersKwargs], + ) -> BaseModelOutput: + r""" + Args: + inputs_embeds (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`): + Flattened feature map (output of the backbone + projection layer) that is passed to the encoder. + """ + feature_maps = inputs_embeds + + # AIFI: Apply transformer encoder to specified feature levels + if self.config.encoder_layers > 0: + for i, enc_ind in enumerate(self.encode_proj_layers): + feature_maps[enc_ind] = self.aifi[i](feature_maps[enc_ind], **kwargs) + + # top-down FPN + fpn_feature_maps = [feature_maps[-1]] + for idx, (lateral_conv, fpn_block) in enumerate(zip(self.lateral_convs, self.fpn_blocks)): + backbone_feature_map = feature_maps[self.num_fpn_stages - idx - 1] + top_fpn_feature_map = fpn_feature_maps[-1] + # apply lateral block + top_fpn_feature_map = lateral_conv(top_fpn_feature_map) + fpn_feature_maps[-1] = top_fpn_feature_map + # apply fpn block + top_fpn_feature_map = F.interpolate(top_fpn_feature_map, scale_factor=2.0, mode="nearest") + fused_feature_map = torch.concat([top_fpn_feature_map, backbone_feature_map], dim=1) + new_fpn_feature_map = fpn_block(fused_feature_map) + fpn_feature_maps.append(new_fpn_feature_map) + + fpn_feature_maps.reverse() + + # bottom-up PAN + pan_feature_maps = [fpn_feature_maps[0]] + for idx, (downsample_conv, pan_block) in enumerate(zip(self.downsample_convs, self.pan_blocks)): + top_pan_feature_map = pan_feature_maps[-1] + fpn_feature_map = fpn_feature_maps[idx + 1] + downsampled_feature_map = downsample_conv(top_pan_feature_map) + fused_feature_map = torch.concat([downsampled_feature_map, fpn_feature_map], dim=1) + new_pan_feature_map = pan_block(fused_feature_map) + pan_feature_maps.append(new_pan_feature_map) + + return BaseModelOutput(last_hidden_state=pan_feature_maps) + + +def inverse_sigmoid(x, eps=1e-5): + x = x.clamp(min=0, max=1) + x1 = x.clamp(min=eps) + x2 = (1 - x).clamp(min=eps) + return torch.log(x1 / x2) + + +class PPDocLayoutV2Decoder(PPDocLayoutV2PreTrainedModel): + _can_record_outputs = { + "hidden_states": PPDocLayoutV2DecoderLayer, + "attentions": PPDocLayoutV2SelfAttention, + "cross_attentions": PPDocLayoutV2MultiscaleDeformableAttention, + } + + def __init__(self, config: PPDocLayoutV2Config): + super().__init__(config) + + self.dropout = config.dropout + self.layers = nn.ModuleList([PPDocLayoutV2DecoderLayer(config) for _ in range(config.decoder_layers)]) + self.query_pos_head = PPDocLayoutV2MLPPredictionHead(4, 2 * config.d_model, config.d_model, num_layers=2) + + # hack implementation for iterative bounding box refinement and two-stage Deformable DETR + self.bbox_embed = None + self.class_embed = None + + # Initialize weights and apply final processing + self.post_init() + + @merge_with_config_defaults + @capture_outputs + def forward( + self, + inputs_embeds=None, + encoder_hidden_states=None, + encoder_attention_mask=None, + reference_points=None, + spatial_shapes=None, + spatial_shapes_list=None, + level_start_index=None, + **kwargs: Unpack[TransformersKwargs], + ): + r""" + Args: + inputs_embeds (`torch.FloatTensor` of shape `(batch_size, num_queries, hidden_size)`): + The query embeddings that are passed into the decoder. + encoder_hidden_states (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*): + Sequence of hidden-states at the output of the last layer of the encoder. Used in the cross-attention + of the decoder. + encoder_attention_mask (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Mask to avoid performing cross-attention on padding pixel_values of the encoder. Mask values selected + in `[0, 1]`: + - 1 for pixels that are real (i.e. **not masked**), + - 0 for pixels that are padding (i.e. **masked**). + reference_points (`torch.FloatTensor` of shape `(batch_size, num_queries, 4)` is `as_two_stage` else `(batch_size, num_queries, 2)` or , *optional*): + Reference point in range `[0, 1]`, top-left (0,0), bottom-right (1, 1), including padding area. + spatial_shapes (`torch.FloatTensor` of shape `(num_feature_levels, 2)`): + Spatial shapes of the feature maps. + level_start_index (`torch.LongTensor` of shape `(num_feature_levels)`, *optional*): + Indexes for the start of each feature level. In range `[0, sequence_length]`. + """ + if inputs_embeds is not None: + hidden_states = inputs_embeds + + # decoder layers + intermediate = () + intermediate_reference_points = () + intermediate_logits = () + + reference_points = F.sigmoid(reference_points) + + # https://github.com/lyuwenyu/RT-DETR/blob/94f5e16708329d2f2716426868ec89aa774af016/PPDocLayoutV2_pytorch/src/zoo/PPDocLayoutV2/PPDocLayoutV2_decoder.py#L252 + for idx, decoder_layer in enumerate(self.layers): + reference_points_input = reference_points.unsqueeze(2) + object_queries_position_embeddings = self.query_pos_head(reference_points) + + hidden_states = decoder_layer( + hidden_states, + object_queries_position_embeddings=object_queries_position_embeddings, + encoder_hidden_states=encoder_hidden_states, + reference_points=reference_points_input, + spatial_shapes=spatial_shapes, + spatial_shapes_list=spatial_shapes_list, + level_start_index=level_start_index, + encoder_attention_mask=encoder_attention_mask, + **kwargs, + ) + + # hack implementation for iterative bounding box refinement + if self.bbox_embed is not None: + predicted_corners = self.bbox_embed[idx](hidden_states) + new_reference_points = F.sigmoid(predicted_corners + inverse_sigmoid(reference_points)) + reference_points = new_reference_points.detach() + + intermediate += (hidden_states,) + intermediate_reference_points += ( + (new_reference_points,) if self.bbox_embed is not None else (reference_points,) + ) + + if self.class_embed is not None: + logits = self.class_embed[idx](hidden_states) + intermediate_logits += (logits,) + + # Keep batch_size as first dimension + intermediate = torch.stack(intermediate, dim=1) + intermediate_reference_points = torch.stack(intermediate_reference_points, dim=1) + if self.class_embed is not None: + intermediate_logits = torch.stack(intermediate_logits, dim=1) + + return PPDocLayoutV2DecoderOutput( + last_hidden_state=hidden_states, + intermediate_hidden_states=intermediate, + intermediate_logits=intermediate_logits, + intermediate_reference_points=intermediate_reference_points, + ) + + +def get_contrastive_denoising_training_group( + targets, + num_classes, + num_queries, + class_embed, + num_denoising_queries=100, + label_noise_ratio=0.5, + box_noise_scale=1.0, +): + """ + Creates a contrastive denoising training group using ground-truth samples. It adds noise to labels and boxes. + + Args: + targets (`list[dict]`): + The target objects, each containing 'class_labels' and 'boxes' for objects in an image. + num_classes (`int`): + Total number of classes in the dataset. + num_queries (`int`): + Number of query slots in the transformer. + class_embed (`callable`): + A function or a model layer to embed class labels. + num_denoising_queries (`int`, *optional*, defaults to 100): + Number of denoising queries. + label_noise_ratio (`float`, *optional*, defaults to 0.5): + Ratio of noise applied to labels. + box_noise_scale (`float`, *optional*, defaults to 1.0): + Scale of noise applied to bounding boxes. + Returns: + `tuple` comprising various elements: + - **input_query_class** (`torch.FloatTensor`) -- + Class queries with applied label noise. + - **input_query_bbox** (`torch.FloatTensor`) -- + Bounding box queries with applied box noise. + - **attn_mask** (`torch.FloatTensor`) -- + Attention mask for separating denoising and reconstruction queries. + - **denoising_meta_values** (`dict`) -- + Metadata including denoising positive indices, number of groups, and split sizes. + """ + + if num_denoising_queries <= 0: + return None, None, None, None + + num_ground_truths = [len(t["class_labels"]) for t in targets] + device = targets[0]["class_labels"].device + + max_gt_num = max(num_ground_truths) + if max_gt_num == 0: + return None, None, None, None + + num_groups_denoising_queries = num_denoising_queries // max_gt_num + num_groups_denoising_queries = 1 if num_groups_denoising_queries == 0 else num_groups_denoising_queries + # pad gt to max_num of a batch + batch_size = len(num_ground_truths) + + input_query_class = torch.full([batch_size, max_gt_num], num_classes, dtype=torch.int32, device=device) + input_query_bbox = torch.zeros([batch_size, max_gt_num, 4], device=device) + pad_gt_mask = torch.zeros([batch_size, max_gt_num], dtype=torch.bool, device=device) + + for i in range(batch_size): + num_gt = num_ground_truths[i] + if num_gt > 0: + input_query_class[i, :num_gt] = targets[i]["class_labels"] + input_query_bbox[i, :num_gt] = targets[i]["boxes"] + pad_gt_mask[i, :num_gt] = 1 + # each group has positive and negative queries. + input_query_class = input_query_class.tile([1, 2 * num_groups_denoising_queries]) + input_query_bbox = input_query_bbox.tile([1, 2 * num_groups_denoising_queries, 1]) + pad_gt_mask = pad_gt_mask.tile([1, 2 * num_groups_denoising_queries]) + # positive and negative mask + negative_gt_mask = torch.zeros([batch_size, max_gt_num * 2, 1], device=device) + negative_gt_mask[:, max_gt_num:] = 1 + negative_gt_mask = negative_gt_mask.tile([1, num_groups_denoising_queries, 1]) + positive_gt_mask = 1 - negative_gt_mask + # contrastive denoising training positive index + positive_gt_mask = positive_gt_mask.squeeze(-1) * pad_gt_mask + denoise_positive_idx = torch.nonzero(positive_gt_mask)[:, 1] + denoise_positive_idx = torch.split( + denoise_positive_idx, [n * num_groups_denoising_queries for n in num_ground_truths] + ) + # total denoising queries + num_denoising_queries = torch_int(max_gt_num * 2 * num_groups_denoising_queries) + + if label_noise_ratio > 0: + mask = torch.rand_like(input_query_class, dtype=torch.float) < (label_noise_ratio * 0.5) + # randomly put a new one here + new_label = torch.randint_like(mask, 0, num_classes, dtype=input_query_class.dtype) + input_query_class = torch.where(mask & pad_gt_mask, new_label, input_query_class) + + if box_noise_scale > 0: + known_bbox = center_to_corners_format(input_query_bbox) + diff = torch.tile(input_query_bbox[..., 2:] * 0.5, [1, 1, 2]) * box_noise_scale + rand_sign = torch.randint_like(input_query_bbox, 0, 2) * 2.0 - 1.0 + rand_part = torch.rand_like(input_query_bbox) + rand_part = (rand_part + 1.0) * negative_gt_mask + rand_part * (1 - negative_gt_mask) + rand_part *= rand_sign + known_bbox += rand_part * diff + known_bbox.clip_(min=0.0, max=1.0) + input_query_bbox = corners_to_center_format(known_bbox) + input_query_bbox = inverse_sigmoid(input_query_bbox) + + input_query_class = class_embed(input_query_class) + + target_size = num_denoising_queries + num_queries + attn_mask = torch.full([target_size, target_size], 0, dtype=torch.float, device=device) + # match query cannot see the reconstruction + attn_mask[num_denoising_queries:, :num_denoising_queries] = -torch.inf + + # reconstructions cannot see each other + for i in range(num_groups_denoising_queries): + idx_block_start = max_gt_num * 2 * i + idx_block_end = max_gt_num * 2 * (i + 1) + attn_mask[idx_block_start:idx_block_end, :idx_block_start] = -torch.inf + attn_mask[idx_block_start:idx_block_end, idx_block_end:num_denoising_queries] = -torch.inf + + denoising_meta_values = { + "dn_positive_idx": denoise_positive_idx, + "dn_num_group": num_groups_denoising_queries, + "dn_num_split": [num_denoising_queries, num_queries], + } + + return input_query_class, input_query_bbox, attn_mask, denoising_meta_values + + +@auto_docstring( + custom_intro=""" + PP-DocLayoutV2 Model (consisting of a backbone and encoder-decoder) outputting raw hidden states without any head on top. + """ +) +class PPDocLayoutV2Model(PPDocLayoutV2PreTrainedModel): + def __init__(self, config: PPDocLayoutV2Config): + super().__init__(config) + + # Create backbone + self.backbone = PPDocLayoutV2ConvEncoder(config) + intermediate_channel_sizes = self.backbone.intermediate_channel_sizes + + # Create encoder input projection layers + # https://github.com/lyuwenyu/RT-DETR/blob/94f5e16708329d2f2716426868ec89aa774af016/PPDocLayoutV2_pytorch/src/zoo/PPDocLayoutV2/hybrid_encoder.py#L212 + num_backbone_outs = len(intermediate_channel_sizes) + encoder_input_proj_list = [] + for i in range(num_backbone_outs): + in_channels = intermediate_channel_sizes[i] + encoder_input_proj_list.append( + nn.Sequential( + nn.Conv2d(in_channels, config.encoder_hidden_dim, kernel_size=1, bias=False), + nn.BatchNorm2d(config.encoder_hidden_dim), + ) + ) + self.encoder_input_proj = nn.ModuleList(encoder_input_proj_list) + + # Create encoder + self.encoder = PPDocLayoutV2HybridEncoder(config) + + # denoising part + if config.num_denoising > 0: + self.denoising_class_embed = nn.Embedding( + config.num_labels + 1, config.d_model, padding_idx=config.num_labels + ) + + # decoder embedding + if config.learn_initial_query: + self.weight_embedding = nn.Embedding(config.num_queries, config.d_model) + + # encoder head + self.enc_output = nn.Sequential( + nn.Linear(config.d_model, config.d_model), + nn.LayerNorm(config.d_model, eps=config.layer_norm_eps), + ) + self.enc_score_head = nn.Linear(config.d_model, config.num_labels) + self.enc_bbox_head = PPDocLayoutV2MLPPredictionHead(config.d_model, config.d_model, 4, num_layers=3) + + # init encoder output anchors and valid_mask + if config.anchor_image_size: + self.anchors, self.valid_mask = self.generate_anchors(dtype=self.dtype) + + # Create decoder input projection layers + # https://github.com/lyuwenyu/RT-DETR/blob/94f5e16708329d2f2716426868ec89aa774af016/PPDocLayoutV2_pytorch/src/zoo/PPDocLayoutV2/PPDocLayoutV2_decoder.py#L412 + num_backbone_outs = len(config.decoder_in_channels) + decoder_input_proj_list = [] + for i in range(num_backbone_outs): + in_channels = config.decoder_in_channels[i] + decoder_input_proj_list.append( + nn.Sequential( + nn.Conv2d(in_channels, config.d_model, kernel_size=1, bias=False), + nn.BatchNorm2d(config.d_model, config.batch_norm_eps), + ) + ) + for _ in range(config.num_feature_levels - num_backbone_outs): + decoder_input_proj_list.append( + nn.Sequential( + nn.Conv2d(in_channels, config.d_model, kernel_size=3, stride=2, padding=1, bias=False), + nn.BatchNorm2d(config.d_model, config.batch_norm_eps), + ) + ) + in_channels = config.d_model + self.decoder_input_proj = nn.ModuleList(decoder_input_proj_list) + + # decoder + self.decoder = PPDocLayoutV2Decoder(config) + self.denoising_class_embed = nn.Embedding(config.num_labels, config.d_model) + + self.post_init() + + def freeze_backbone(self): + for param in self.backbone.parameters(): + param.requires_grad_(False) + + def unfreeze_backbone(self): + for param in self.backbone.parameters(): + param.requires_grad_(True) + + @compile_compatible_method_lru_cache(maxsize=32) + def generate_anchors(self, spatial_shapes=None, grid_size=0.05, device="cpu", dtype=torch.float32): + if spatial_shapes is None: + spatial_shapes = [ + [int(self.config.anchor_image_size[0] / s), int(self.config.anchor_image_size[1] / s)] + for s in self.config.feat_strides + ] + anchors = [] + for level, (height, width) in enumerate(spatial_shapes): + grid_y, grid_x = torch.meshgrid( + torch.arange(end=height, device=device).to(dtype), + torch.arange(end=width, device=device).to(dtype), + indexing="ij", + ) + grid_xy = torch.stack([grid_x, grid_y], -1) + grid_xy = grid_xy.unsqueeze(0) + 0.5 + grid_xy[..., 0] /= width + grid_xy[..., 1] /= height + wh = torch.ones_like(grid_xy) * grid_size * (2.0**level) + anchors.append(torch.concat([grid_xy, wh], -1).reshape(-1, height * width, 4)) + # define the valid range for anchor coordinates + eps = 1e-2 + anchors = torch.concat(anchors, 1) + valid_mask = ((anchors > eps) * (anchors < 1 - eps)).all(-1, keepdim=True) + anchors = torch.log(anchors / (1 - anchors)) + anchors = torch.where(valid_mask, anchors, torch.tensor(torch.finfo(dtype).max, dtype=dtype, device=device)) + + return anchors, valid_mask + + @auto_docstring + @can_return_tuple + def forward( + self, + pixel_values: torch.FloatTensor, + pixel_mask: torch.LongTensor | None = None, + encoder_outputs: torch.FloatTensor | None = None, + inputs_embeds: torch.FloatTensor | None = None, + labels: list[dict] | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.FloatTensor] | PPDocLayoutV2ModelOutput: + r""" + inputs_embeds (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*): + Optionally, instead of passing the flattened feature map (output of the backbone + projection layer), you + can choose to directly pass a flattened representation of an image. + labels (`list[Dict]` of len `(batch_size,)`, *optional*): + Labels for computing the bipartite matching loss. List of dicts, each dictionary containing at least the + following 2 keys: 'class_labels' and 'boxes' (the class labels and bounding boxes of an image in the batch + respectively). The class labels themselves should be a `torch.LongTensor` of len `(number of bounding boxes + in the image,)` and the boxes a `torch.FloatTensor` of shape `(number of bounding boxes in the image, 4)`. + + Examples: + + ```python + >>> from transformers import AutoImageProcessor, PPDocLayoutV2Model + >>> from PIL import Image + >>> import requests + + >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg" + >>> image = Image.open(requests.get(url, stream=True).raw) + + >>> image_processor = AutoImageProcessor.from_pretrained("PekingU/PPDocLayoutV2_r50vd") + >>> model = PPDocLayoutV2Model.from_pretrained("PekingU/PPDocLayoutV2_r50vd") + + >>> inputs = image_processor(images=image, return_tensors="pt") + + >>> outputs = model(**inputs) + + >>> last_hidden_states = outputs.last_hidden_state + >>> list(last_hidden_states.shape) + [1, 300, 256] + ```""" + if pixel_values is None and inputs_embeds is None: + raise ValueError("You have to specify either pixel_values or inputs_embeds") + + if inputs_embeds is None: + batch_size, num_channels, height, width = pixel_values.shape + device = pixel_values.device + if pixel_mask is None: + pixel_mask = torch.ones(((batch_size, height, width)), device=device) + features = self.backbone(pixel_values, pixel_mask) + proj_feats = [self.encoder_input_proj[level](source) for level, (source, mask) in enumerate(features)] + else: + batch_size = inputs_embeds.shape[0] + device = inputs_embeds.device + proj_feats = inputs_embeds + + if encoder_outputs is None: + encoder_outputs = self.encoder( + proj_feats, + **kwargs, + ) + # If the user passed a tuple for encoder_outputs, we wrap it in a BaseModelOutput + elif not isinstance(encoder_outputs, BaseModelOutput): + encoder_outputs = BaseModelOutput( + last_hidden_state=encoder_outputs[0], + hidden_states=encoder_outputs[1] if len(encoder_outputs) > 1 else None, + attentions=encoder_outputs[2] if len(encoder_outputs) > 2 else None, + ) + + # Equivalent to def _get_encoder_input + # https://github.com/lyuwenyu/RT-DETR/blob/94f5e16708329d2f2716426868ec89aa774af016/PPDocLayoutV2_pytorch/src/zoo/PPDocLayoutV2/PPDocLayoutV2_decoder.py#L412 + sources = [] + for level, source in enumerate(encoder_outputs.last_hidden_state): + sources.append(self.decoder_input_proj[level](source)) + + # Lowest resolution feature maps are obtained via 3x3 stride 2 convolutions on the final stage + if self.config.num_feature_levels > len(sources): + _len_sources = len(sources) + sources.append(self.decoder_input_proj[_len_sources](encoder_outputs.last_hidden_state)[-1]) + for i in range(_len_sources + 1, self.config.num_feature_levels): + sources.append(self.decoder_input_proj[i](encoder_outputs.last_hidden_state[-1])) + + # Prepare encoder inputs (by flattening) + source_flatten = [] + spatial_shapes_list = [] + spatial_shapes = torch.empty((len(sources), 2), device=device, dtype=torch.long) + for level, source in enumerate(sources): + height, width = source.shape[-2:] + spatial_shapes[level, 0] = height + spatial_shapes[level, 1] = width + spatial_shapes_list.append((height, width)) + source = source.flatten(2).transpose(1, 2) + source_flatten.append(source) + source_flatten = torch.cat(source_flatten, 1) + level_start_index = torch.cat((spatial_shapes.new_zeros((1,)), spatial_shapes.prod(1).cumsum(0)[:-1])) + + # prepare denoising training + if self.training and self.config.num_denoising > 0 and labels is not None: + ( + denoising_class, + denoising_bbox_unact, + attention_mask, + denoising_meta_values, + ) = get_contrastive_denoising_training_group( + targets=labels, + num_classes=self.config.num_labels, + num_queries=self.config.num_queries, + class_embed=self.denoising_class_embed, + num_denoising_queries=self.config.num_denoising, + label_noise_ratio=self.config.label_noise_ratio, + box_noise_scale=self.config.box_noise_scale, + ) + else: + denoising_class, denoising_bbox_unact, attention_mask, denoising_meta_values = None, None, None, None + + batch_size = len(source_flatten) + device = source_flatten.device + dtype = source_flatten.dtype + + # prepare input for decoder + if self.training or self.config.anchor_image_size is None: + # Pass spatial_shapes as tuple to make it hashable and make sure + # lru_cache is working for generate_anchors() + spatial_shapes_tuple = tuple(spatial_shapes_list) + anchors, valid_mask = self.generate_anchors(spatial_shapes_tuple, device=device, dtype=dtype) + else: + anchors, valid_mask = self.anchors, self.valid_mask + anchors, valid_mask = anchors.to(device, dtype), valid_mask.to(device, dtype) + + # use the valid_mask to selectively retain values in the feature map where the mask is `True` + memory = valid_mask.to(source_flatten.dtype) * source_flatten + + output_memory = self.enc_output(memory) + + enc_outputs_class = self.enc_score_head(output_memory) + enc_outputs_coord_logits = self.enc_bbox_head(output_memory) + anchors + + _, topk_ind = torch.topk(enc_outputs_class.max(-1).values, self.config.num_queries, dim=1) + + reference_points_unact = enc_outputs_coord_logits.gather( + dim=1, index=topk_ind.unsqueeze(-1).repeat(1, 1, enc_outputs_coord_logits.shape[-1]) + ) + + enc_topk_bboxes = F.sigmoid(reference_points_unact) + if denoising_bbox_unact is not None: + reference_points_unact = torch.concat([denoising_bbox_unact, reference_points_unact], 1) + + enc_topk_logits = enc_outputs_class.gather( + dim=1, index=topk_ind.unsqueeze(-1).repeat(1, 1, enc_outputs_class.shape[-1]) + ) + + # extract region features + if self.config.learn_initial_query: + target = self.weight_embedding.tile([batch_size, 1, 1]) + else: + target = output_memory.gather(dim=1, index=topk_ind.unsqueeze(-1).repeat(1, 1, output_memory.shape[-1])) + target = target.detach() + + if denoising_class is not None: + target = torch.concat([denoising_class, target], 1) + + init_reference_points = reference_points_unact.detach() + + # decoder + decoder_outputs = self.decoder( + inputs_embeds=target, + encoder_hidden_states=source_flatten, + encoder_attention_mask=attention_mask, + reference_points=init_reference_points, + spatial_shapes=spatial_shapes, + spatial_shapes_list=spatial_shapes_list, + level_start_index=level_start_index, + **kwargs, + ) + + return PPDocLayoutV2ModelOutput( + last_hidden_state=decoder_outputs.last_hidden_state, + intermediate_hidden_states=decoder_outputs.intermediate_hidden_states, + intermediate_logits=decoder_outputs.intermediate_logits, + intermediate_reference_points=decoder_outputs.intermediate_reference_points, + intermediate_predicted_corners=decoder_outputs.intermediate_predicted_corners, + initial_reference_points=decoder_outputs.initial_reference_points, + decoder_hidden_states=decoder_outputs.hidden_states, + decoder_attentions=decoder_outputs.attentions, + cross_attentions=decoder_outputs.cross_attentions, + encoder_last_hidden_state=encoder_outputs.last_hidden_state, + encoder_hidden_states=encoder_outputs.hidden_states, + encoder_attentions=encoder_outputs.attentions, + init_reference_points=init_reference_points, + enc_topk_logits=enc_topk_logits, + enc_topk_bboxes=enc_topk_bboxes, + enc_outputs_class=enc_outputs_class, + enc_outputs_coord_logits=enc_outputs_coord_logits, + denoising_meta_values=denoising_meta_values, + ) + + +@auto_docstring( + custom_intro=""" + PP-DocLayoutV2 Model (consisting of a backbone and encoder-decoder) outputting bounding boxes, logits and order_logits to be further + decoded into scores, classes and their reading order. + """ +) +class PPDocLayoutV2ForObjectDetection(PPDocLayoutV2PreTrainedModel): + # When using clones, all layers > 0 will be clones, but layer 0 *is* required + # We can't initialize the model on meta device as some weights are modified during the initialization + _no_split_modules = None + _keys_to_ignore_on_load_missing = ["num_batches_tracked", "rel_pos_y_bias", "rel_pos_x_bias"] + + def __init__(self, config: PPDocLayoutV2Config): + super().__init__(config) + self.model = PPDocLayoutV2Model(config) + num_pred = config.decoder_layers + self.model.decoder.class_embed = nn.ModuleList( + [torch.nn.Linear(config.d_model, config.num_labels) for _ in range(num_pred)] + ) + self.model.decoder.bbox_embed = nn.ModuleList( + [PPDocLayoutV2MLPPredictionHead(config.d_model, config.d_model, 4, num_layers=3) for _ in range(num_pred)] + ) + + self.reading_order = PPDocLayoutV2ReadingOrder(config.reading_order_config) + self.num_queries = config.num_queries + self.config = config + # if two-stage, the last class_embed and bbox_embed is for region proposal generation + self.post_init() + + def _set_aux_loss(self, outputs_class, outputs_coord): + return [{"logits": a, "pred_boxes": b} for a, b in zip(outputs_class, outputs_coord)] + + @auto_docstring + @can_return_tuple + def forward( + self, + pixel_values: torch.FloatTensor, + pixel_mask: torch.LongTensor | None = None, + encoder_outputs: torch.FloatTensor | None = None, + inputs_embeds: torch.FloatTensor | None = None, + decoder_inputs_embeds: torch.FloatTensor | None = None, + labels: list[dict] | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.FloatTensor] | PPDocLayoutV2ForObjectDetectionOutput: + r""" + inputs_embeds (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*): + Optionally, instead of passing the flattened feature map (output of the backbone + projection layer), you + can choose to directly pass a flattened representation of an image. + decoder_inputs_embeds (`torch.FloatTensor` of shape `(batch_size, num_queries, hidden_size)`, *optional*): + Optionally, instead of initializing the queries with a tensor of zeros, you can choose to directly pass an + embedded representation. + labels (`list[Dict]` of len `(batch_size,)`, *optional*): + Labels for computing the bipartite matching loss. List of dicts, each dictionary containing at least the + following 2 keys: 'class_labels' and 'boxes' (the class labels and bounding boxes of an image in the batch + respectively). The class labels themselves should be a `torch.LongTensor` of len `(number of bounding boxes + in the image,)` and the boxes a `torch.FloatTensor` of shape `(number of bounding boxes in the image, 4)`. + + Examples: + + ```python + >>> from transformers import AutoModelForObjectDetection, AutoImageProcessor + >>> from PIL import Image + >>> import requests + >>> import torch + + >>> url = "https://paddle-model-ecology.bj.bcebos.com/paddlex/imgs/demo_image/layout_demo.jpg" + >>> image = Image.open(requests.get(url, stream=True).raw) + + >>> model_path = "PaddlePaddle/PP-DocLayoutV2_safetensors" + >>> image_processor = AutoImageProcessor.from_pretrained(model_path) + >>> model = AutoModelForObjectDetection.from_pretrained(model_path) + + >>> # prepare image for the model + >>> inputs = image_processor(images=[image], return_tensors="pt") + + >>> # forward pass + >>> outputs = model(**inputs) + + >>> # convert outputs (bounding boxes and class logits) to Pascal VOC format (xmin, ymin, xmax, ymax) + >>> results = image_processor.post_process_object_detection(outputs, target_sizes=torch.tensor([image.size[::-1]])) + + >>> # print outputs + >>> for result in results: + ... for idx, (score, label_id, box) in enumerate(zip(result["scores"], result["labels"], result["boxes"])): + ... score, label = score.item(), label_id.item() + ... box = [round(i, 2) for i in box.tolist()] + ... print(f"Order {idx + 1}: {model.config.id2label[label]}: {score:.2f} {box}") + Order 1: text: 0.99 [335.39, 184.26, 896.49, 654.48] + Order 2: paragraph_title: 0.97 [337.14, 683.49, 869.42, 798.27] + Order 3: text: 0.99 [335.71, 843.04, 891.17, 1454.15] + Order 4: text: 0.99 [920.42, 185.53, 1476.39, 464.25] + Order 5: text: 0.98 [920.62, 483.75, 1480.52, 765.34] + Order 6: text: 0.98 [920.58, 846.75, 1481.94, 1220.53] + Order 7: text: 0.97 [921.12, 1239.27, 1468.87, 1377.33] + Order 8: footnote: 0.82 [334.58, 1614.67, 1483.84, 1731.61] + Order 9: text: 0.51 [334.58, 1614.67, 1483.84, 1731.61] + Order 10: footnote: 0.83 [334.7, 1757.26, 1471.07, 1845.33] + Order 11: text: 0.87 [336.65, 1910.28, 661.33, 1939.92] + Order 12: footnote: 0.95 [336.16, 2114.52, 1450.28, 2171.74] + Order 13: number: 0.87 [106.04, 2257.37, 136.05, 2281.98] + Order 14: footer: 0.93 [338.6, 2255.94, 985.67, 2283.57] + ```""" + outputs = self.model( + pixel_values, + pixel_mask=pixel_mask, + encoder_outputs=encoder_outputs, + inputs_embeds=inputs_embeds, + decoder_inputs_embeds=decoder_inputs_embeds, + labels=labels, + **kwargs, + ) + + intermediate_reference_points = outputs.intermediate_reference_points + intermediate_logits = outputs.intermediate_logits + raw_bboxes = intermediate_reference_points[:, -1] + logits = intermediate_logits[:, -1] + + box_centers, box_sizes = raw_bboxes.split(2, dim=-1) + bboxes = torch.cat([box_centers - 0.5 * box_sizes, box_centers + 0.5 * box_sizes], dim=-1) * 1000 + bboxes = bboxes.clamp_(0.0, 1000.0) + + max_logits, class_ids = logits.max(dim=-1) + max_probs = max_logits.sigmoid() + + class_thresholds = torch.tensor(self.config.class_thresholds, dtype=torch.float32, device=logits.device) + thresholds = class_thresholds[class_ids] + mask = max_probs >= thresholds + + indices = torch.argsort(mask.to(torch.int8), dim=1, descending=True) + + sorted_class_ids = torch.take_along_dim(class_ids, indices, dim=1) + sorted_boxes = torch.take_along_dim(bboxes, indices[..., None].expand(-1, -1, 4), dim=1) + pred_boxes = torch.take_along_dim(raw_bboxes, indices[..., None].expand(-1, -1, 4), dim=1) + logits = torch.take_along_dim(logits, indices[..., None].expand(-1, -1, logits.size(-1)), dim=1) + + sorted_mask = torch.take_along_dim(mask, indices, dim=1) + + pad_boxes = torch.where(sorted_mask[..., None], sorted_boxes, torch.zeros_like(sorted_boxes)) + pad_class_ids = torch.where(sorted_mask, sorted_class_ids, torch.zeros_like(sorted_class_ids)) + + class_order = torch.tensor(self.config.class_order, dtype=torch.int32, device=logits.device) + pad_class_ids = class_order[pad_class_ids] + + order_logits = self.reading_order( + boxes=pad_boxes, + labels=pad_class_ids, + mask=mask, + ) + order_logits = order_logits[:, :, : self.num_queries] + + if labels is not None: + raise ValueError("PPDocLayoutV2ForObjectDetection does not support training") + + return PPDocLayoutV2ForObjectDetectionOutput( + logits=logits, + pred_boxes=pred_boxes, + order_logits=order_logits, + last_hidden_state=outputs.last_hidden_state, + intermediate_hidden_states=outputs.intermediate_hidden_states, + intermediate_logits=outputs.intermediate_logits, + intermediate_reference_points=outputs.intermediate_reference_points, + intermediate_predicted_corners=outputs.intermediate_predicted_corners, + initial_reference_points=outputs.initial_reference_points, + decoder_hidden_states=outputs.decoder_hidden_states, + decoder_attentions=outputs.decoder_attentions, + cross_attentions=outputs.cross_attentions, + encoder_last_hidden_state=outputs.encoder_last_hidden_state, + encoder_hidden_states=outputs.encoder_hidden_states, + encoder_attentions=outputs.encoder_attentions, + init_reference_points=outputs.init_reference_points, + enc_topk_logits=outputs.enc_topk_logits, + enc_topk_bboxes=outputs.enc_topk_bboxes, + enc_outputs_class=outputs.enc_outputs_class, + enc_outputs_coord_logits=outputs.enc_outputs_coord_logits, + denoising_meta_values=outputs.denoising_meta_values, + ) + + +__all__ = [ + "PPDocLayoutV2ForObjectDetection", + "PPDocLayoutV2Model", + "PPDocLayoutV2PreTrainedModel", + "PPDocLayoutV2ReadingOrder", +] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pp_doclayout_v2/modular_pp_doclayout_v2.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pp_doclayout_v2/modular_pp_doclayout_v2.py new file mode 100644 index 0000000000000000000000000000000000000000..bd7fc09e4f66832213e2c2690c63d58a7a618a93 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pp_doclayout_v2/modular_pp_doclayout_v2.py @@ -0,0 +1,1161 @@ +# Copyright 2026 The PaddlePaddle Team and The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import math +from dataclasses import dataclass +from typing import Optional + +import torch +from torch import nn + +from ... import initialization as init +from ...backbone_utils import consolidate_backbone_kwargs_to_config +from ...configuration_utils import PreTrainedConfig +from ...masking_utils import create_bidirectional_mask +from ...processing_utils import Unpack +from ...utils import ( + ModelOutput, + TransformersKwargs, + auto_docstring, + can_return_tuple, + logging, +) +from ...utils.generic import TensorType +from ..auto import AutoConfig +from ..layoutlmv3.modeling_layoutlmv3 import ( + LayoutLMv3Attention, + LayoutLMv3Encoder, + LayoutLMv3Intermediate, + LayoutLMv3Layer, + LayoutLMv3Output, + LayoutLMv3SelfAttention, + LayoutLMv3SelfOutput, + LayoutLMv3TextEmbeddings, +) +from ..pp_doclayout_v3.image_processing_pp_doclayout_v3_fast import PPDocLayoutV3ImageProcessorFast +from ..pp_doclayout_v3.modeling_pp_doclayout_v3 import PPDocLayoutV3GlobalPointer +from ..rt_detr.modeling_rt_detr import ( + RTDetrForObjectDetection, + RTDetrMLPPredictionHead, + RTDetrModel, + RTDetrModelOutput, + RTDetrPreTrainedModel, +) + + +logger = logging.get_logger(__name__) + + +class PPDocLayoutV2ReadingOrderConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`PPDocLayoutV2ReadingOrder`]. + + It is used to instantiate the reading order sub-module of the PP-DocLayoutV2 model. This configuration defines the architecture and hyperparameters specific to the reading order detection task within the larger PP-DocLayoutV2 framework. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + hidden_size (`int`, *optional*, defaults to 512): + Dimension of the encoder layers and the pooled layer. + num_attention_heads (`int`, *optional*, defaults to 8): + Number of attention heads for each attention layer. + attention_probs_dropout_prob (`float`, *optional*, defaults to 0.1): + The dropout ratio for the attention probabilities. + has_relative_attention_bias (`bool`, *optional*, defaults to `True`): + Whether or not to use a relative attention bias in the self-attention mechanism. + has_spatial_attention_bias (`bool`, *optional*, defaults to `True`): + Whether or not to use a spatial attention bias in the self-attention mechanism. + layer_norm_eps (`float`, *optional*, defaults to 1e-05): + The epsilon used by the layer normalization layers. + hidden_dropout_prob (`float`, *optional*, defaults to 0.1): + The dropout probability for all fully connected layers in the embeddings, encoder, and pooler. + intermediate_size (`int`, *optional*, defaults to 2048): + Dimension of the "intermediate" (i.e., feed-forward) layer in the Transformer encoder. + hidden_act (`str` or `function`, *optional*, defaults to `"gelu"`): + The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`, + `"relu"`, `"silu"` and `"gelu_new"` are supported. + num_hidden_layers (`int`, *optional*, defaults to 6): + Number of the hidden layers. + rel_pos_bins (`int`, *optional*, defaults to 32): + The number of relative position bins to be used in the self-attention mechanism. + max_rel_pos (`int`, *optional*, defaults to 128): + The maximum number of relative positions to be used in the self-attention mechanism. + rel_2d_pos_bins (`int`, *optional*, defaults to 64): + The number of 2D relative position bins in the self-attention mechanism. + max_rel_2d_pos (`int`, *optional*, defaults to 256): + The maximum number of relative 2D positions in the self-attention mechanism. + max_position_embeddings (`int`, *optional*, defaults to 514): + The maximum sequence length that this model might ever be used with. Typically set this to something large + just in case (e.g., 512 or 1024 or 2048). + max_2d_position_embeddings (`int`, *optional*, defaults to 1024): + The maximum value that the 2D position embedding might ever be used with. Typically set this to something + large just in case (e.g., 1024). + type_vocab_size (`int`, *optional*, defaults to 1): + The vocabulary size of the `token_type_ids`. + vocab_size (`int`, *optional*, defaults to 4): + Vocabulary size of the model. Defines the number of different tokens that can be represented by the `inputs_ids`. + initializer_range (`float`, *optional*, defaults to 0.01): + The standard deviation of the truncated_normal_initializer for initializing all weight matrices. + start_token_id (`int`, *optional*, defaults to 0): + Token id representing the start of a sequence. + pad_token_id (`int`, *optional*, defaults to 1): + Token id used for padding the input sequences. + end_token_id (`int`, *optional*, defaults to 2): + Token id representing the end of a sequence. + pred_token_id (`int`, *optional*, defaults to 3): + Token id representing valid prediction positions (placeholders) in the sequence. + coordinate_size (`int`, *optional*, defaults to 171): + Dimension of the coordinate embeddings. + shape_size (`int`, *optional*, defaults to 170): + Dimension of the width and height embeddings. + num_classes (`int`, *optional*, defaults to 20): + Number of labels or classes for the layout elements. + relation_bias_embed_dim (`int`, *optional*, defaults to 16): + Embedding dimension for the relation bias. + relation_bias_theta (`float`, *optional*, defaults to 10000): + Temperature parameter used for relation bias scaling. + relation_bias_scale (`float`, *optional*, defaults to 100): + Scale parameter for the relation bias. + global_pointer_head_size (`int`, *optional*, defaults to 64): + The size of the global pointer head. + gp_dropout_value (`float`, *optional*, defaults to 0.0): + The dropout probability in the global pointer head. + """ + + def __init__( + self, + hidden_size=512, + num_attention_heads=8, + attention_probs_dropout_prob=0.1, + has_relative_attention_bias=False, + has_spatial_attention_bias=True, + layer_norm_eps=1e-5, + hidden_dropout_prob=0.1, + intermediate_size=2048, + hidden_act="gelu", + num_hidden_layers=6, + rel_pos_bins=32, + max_rel_pos=128, + rel_2d_pos_bins=64, + max_rel_2d_pos=256, + max_position_embeddings=514, + max_2d_position_embeddings=1024, + type_vocab_size=1, + vocab_size=4, + initializer_range=0.01, + start_token_id=0, + pad_token_id=1, + end_token_id=2, + pred_token_id=3, + coordinate_size=171, + shape_size=170, + num_classes=20, + relation_bias_embed_dim=16, + relation_bias_theta=10000, + relation_bias_scale=100, + global_pointer_head_size=64, + gp_dropout_value=0.0, + **kwargs, + ): + self.hidden_size = hidden_size + self.num_attention_heads = num_attention_heads + self.attention_probs_dropout_prob = attention_probs_dropout_prob + self.has_relative_attention_bias = has_relative_attention_bias + self.has_spatial_attention_bias = has_spatial_attention_bias + self.layer_norm_eps = layer_norm_eps + self.hidden_dropout_prob = hidden_dropout_prob + self.intermediate_size = intermediate_size + self.hidden_act = hidden_act + self.num_hidden_layers = num_hidden_layers + self.rel_pos_bins = rel_pos_bins + self.max_rel_pos = max_rel_pos + self.rel_2d_pos_bins = rel_2d_pos_bins + self.max_rel_2d_pos = max_rel_2d_pos + self.max_position_embeddings = max_position_embeddings + self.max_2d_position_embeddings = max_2d_position_embeddings + self.type_vocab_size = type_vocab_size + self.vocab_size = vocab_size + self.initializer_range = initializer_range + self.start_token_id = start_token_id + self.pad_token_id = pad_token_id + self.end_token_id = end_token_id + self.pred_token_id = pred_token_id + self.coordinate_size = coordinate_size + self.shape_size = shape_size + self.num_classes = num_classes + self.relation_bias_embed_dim = relation_bias_embed_dim + self.relation_bias_theta = relation_bias_theta + self.relation_bias_scale = relation_bias_scale + self.global_pointer_head_size = global_pointer_head_size + self.gp_dropout_value = gp_dropout_value + + super().__init__(**kwargs) + + +class PPDocLayoutV2Config(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`PP-DocLayoutV2`]. It is used to instantiate a + PP-DocLayoutV2 model according to the specified arguments, defining the model architecture. Instantiating a configuration + with the defaults will yield a similar configuration to that of the PP-DocLayoutV2 + [PaddlePaddle/PP-DocLayoutV2_safetensors](https://huggingface.co/PaddlePaddle/PP-DocLayoutV2_safetensors) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + initializer_range (`float`, *optional*, defaults to 0.01): + The standard deviation of the truncated_normal_initializer for initializing all weight matrices. + initializer_bias_prior_prob (`float`, *optional*): + The prior probability used by the bias initializer to initialize biases for `enc_score_head` and `class_embed`. + If `None`, `prior_prob` computed as `prior_prob = 1 / (num_labels + 1)` while initializing model weights. + layer_norm_eps (`float`, *optional*, defaults to 1e-05): + The epsilon used by the layer normalization layers. + batch_norm_eps (`float`, *optional*, defaults to 1e-05): + The epsilon used by the batch normalization layers. + backbone_config (`Union[dict, "PreTrainedConfig"]`, *optional*, defaults to `RTDetrResNetConfig()`): + The configuration of the backbone model. + freeze_backbone_batch_norms (`bool`, *optional*, defaults to `True`): + Whether to freeze the batch normalization layers in the backbone. + encoder_hidden_dim (`int`, *optional*, defaults to 256): + Dimension of the layers in hybrid encoder. + encoder_in_channels (`list`, *optional*, defaults to `[512, 1024, 2048]`): + Multi level features input for encoder. + feat_strides (`list[int]`, *optional*, defaults to `[8, 16, 32]`): + Strides used in each feature map. + encoder_layers (`int`, *optional*, defaults to 1): + Total of layers to be used by the encoder. + encoder_ffn_dim (`int`, *optional*, defaults to 1024): + Dimension of the "intermediate" (often named feed-forward) layer in decoder. + encoder_attention_heads (`int`, *optional*, defaults to 8): + Number of attention heads for each attention layer in the Transformer encoder. + dropout (`float`, *optional*, defaults to 0.0): + The ratio for all dropout layers. + activation_dropout (`float`, *optional*, defaults to 0.0): + The dropout ratio for activations inside the fully connected layer. + encode_proj_layers (`list[int]`, *optional*, defaults to `[2]`): + Indexes of the projected layers to be used in the encoder. + positional_encoding_temperature (`int`, *optional*, defaults to 10000): + The temperature parameter used to create the positional encodings. + encoder_activation_function (`str`, *optional*, defaults to `"gelu"`): + The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`, + `"relu"`, `"silu"` and `"gelu_new"` are supported. + activation_function (`str`, *optional*, defaults to `"silu"`): + The non-linear activation function (function or string) in the general layer. If string, `"gelu"`, + `"relu"`, `"silu"` and `"gelu_new"` are supported. + eval_size (`tuple[int, int]`, *optional*): + Height and width used to computes the effective height and width of the position embeddings after taking + into account the stride. + normalize_before (`bool`, *optional*, defaults to `False`): + Determine whether to apply layer normalization in the transformer encoder layer before self-attention and + feed-forward modules. + hidden_expansion (`float`, *optional*, defaults to 1.0): + Expansion ratio to enlarge the dimension size of RepVGGBlock and CSPRepLayer. + d_model (`int`, *optional*, defaults to 256): + Dimension of the layers exclude hybrid encoder. + num_queries (`int`, *optional*, defaults to 300): + Number of object queries. + decoder_in_channels (`list`, *optional*, defaults to `[256, 256, 256]`): + Multi level features dimension for decoder + decoder_ffn_dim (`int`, *optional*, defaults to 1024): + Dimension of the "intermediate" (often named feed-forward) layer in decoder. + num_feature_levels (`int`, *optional*, defaults to 3): + The number of input feature levels. + decoder_n_points (`int`, *optional*, defaults to 4): + The number of sampled keys in each feature level for each attention head in the decoder. + decoder_layers (`int`, *optional*, defaults to 6): + Number of decoder layers. + decoder_attention_heads (`int`, *optional*, defaults to 8): + Number of attention heads for each attention layer in the Transformer decoder. + decoder_activation_function (`str`, *optional*, defaults to `"relu"`): + The non-linear activation function (function or string) in the decoder. If string, `"gelu"`, + `"relu"`, `"silu"` and `"gelu_new"` are supported. + attention_dropout (`float`, *optional*, defaults to 0.0): + The dropout ratio for the attention probabilities. + num_denoising (`int`, *optional*, defaults to 100): + The total number of denoising tasks or queries to be used for contrastive denoising. + label_noise_ratio (`float`, *optional*, defaults to 0.5): + The fraction of denoising labels to which random noise should be added. + box_noise_scale (`float`, *optional*, defaults to 1.0): + Scale or magnitude of noise to be added to the bounding boxes. + learn_initial_query (`bool`, *optional*, defaults to `False`): + Indicates whether the initial query embeddings for the decoder should be learned during training + anchor_image_size (`tuple[int, int]`, *optional*): + Height and width of the input image used during evaluation to generate the bounding box anchors. If None, automatic generate anchor is applied. + disable_custom_kernels (`bool`, *optional*, defaults to `True`): + Whether to disable custom kernels. + is_encoder_decoder (`bool`, *optional*, defaults to `True`): + Whether the architecture has an encoder decoder structure. + class_thresholds (`list[float]`, *optional*): + The thresholds for each label. + class_order (`list[int]`, *optional*): + The priority for each label. + reading_order_config (`dict`, *optional*): + The configuration of a `PPDocLayoutV2ReadingOrder`. + + Examples: + + ```python + >>> from transformers import PPDocLayoutV2Config, PPDocLayoutV2ForObjectDetection + + >>> # Initializing a PP-DocLayoutV2 configuration + >>> configuration = PPDocLayoutV2Config() + + >>> # Initializing a model (with random weights) from the configuration + >>> model = PPDocLayoutV2ForObjectDetection(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "pp_doclayout_v2" + sub_configs = {"backbone_config": AutoConfig, "reading_order_config": PPDocLayoutV2ReadingOrderConfig} + + layer_types = ("basic", "bottleneck") + attribute_map = { + "hidden_size": "d_model", + "num_attention_heads": "encoder_attention_heads", + } + + def __init__( + self, + initializer_range=0.01, + initializer_bias_prior_prob=None, + layer_norm_eps=1e-5, + batch_norm_eps=1e-5, + # backbone + backbone_config=None, + freeze_backbone_batch_norms=True, + # encoder HybridEncoder + encoder_hidden_dim=256, + encoder_in_channels=[512, 1024, 2048], + feat_strides=[8, 16, 32], + encoder_layers=1, + encoder_ffn_dim=1024, + encoder_attention_heads=8, + dropout=0.0, + activation_dropout=0.0, + encode_proj_layers=[2], + positional_encoding_temperature=10000, + encoder_activation_function="gelu", + activation_function="silu", + eval_size=None, + normalize_before=False, + hidden_expansion=1.0, + # decoder PPDocLayoutV2Transformer + d_model=256, + num_queries=300, + decoder_in_channels=[256, 256, 256], + decoder_ffn_dim=1024, + num_feature_levels=3, + decoder_n_points=4, + decoder_layers=6, + decoder_attention_heads=8, + decoder_activation_function="relu", + attention_dropout=0.0, + num_denoising=100, + label_noise_ratio=0.5, + box_noise_scale=1.0, + learn_initial_query=False, + anchor_image_size=None, + disable_custom_kernels=True, + is_encoder_decoder=True, + # label + class_thresholds=None, + class_order=None, + reading_order_config=None, + **kwargs, + ): + self.initializer_range = initializer_range + self.initializer_bias_prior_prob = initializer_bias_prior_prob + self.layer_norm_eps = layer_norm_eps + self.batch_norm_eps = batch_norm_eps + + if isinstance(reading_order_config, dict): + self.reading_order_config = self.sub_configs["reading_order_config"](**reading_order_config) + elif reading_order_config is None: + self.reading_order_config = self.sub_configs["reading_order_config"]() + + backbone_config, kwargs = consolidate_backbone_kwargs_to_config( + backbone_config=backbone_config, + default_config_type="hgnet_v2", + default_config_kwargs={ + "arch": "L", + "return_idx": [1, 2, 3], + "freeze_stem_only": True, + "freeze_at": 0, + "freeze_norm": True, + "lr_mult_list": [0, 0.05, 0.05, 0.05, 0.05], + "out_features": ["stage2", "stage3", "stage4"], + }, + **kwargs, + ) + + self.backbone_config = backbone_config + self.freeze_backbone_batch_norms = freeze_backbone_batch_norms + + # ---- encoder ---- + self.encoder_hidden_dim = encoder_hidden_dim + self.encoder_in_channels = list(encoder_in_channels) + self.feat_strides = list(feat_strides) + self.encoder_layers = encoder_layers + self.encoder_ffn_dim = encoder_ffn_dim + self.encoder_attention_heads = encoder_attention_heads + self.dropout = dropout + self.activation_dropout = activation_dropout + self.encode_proj_layers = list(encode_proj_layers) + self.positional_encoding_temperature = positional_encoding_temperature + self.encoder_activation_function = encoder_activation_function + self.activation_function = activation_function + self.eval_size = list(eval_size) if eval_size is not None else None + self.normalize_before = normalize_before + self.hidden_expansion = hidden_expansion + + # ---- decoder ---- + self.d_model = d_model + self.num_queries = num_queries + self.decoder_in_channels = list(decoder_in_channels) + self.decoder_ffn_dim = decoder_ffn_dim + self.num_feature_levels = num_feature_levels + self.decoder_n_points = decoder_n_points + self.decoder_layers = decoder_layers + self.decoder_attention_heads = decoder_attention_heads + self.decoder_activation_function = decoder_activation_function + self.attention_dropout = attention_dropout + self.num_denoising = num_denoising + self.label_noise_ratio = label_noise_ratio + self.box_noise_scale = box_noise_scale + self.learn_initial_query = learn_initial_query + self.anchor_image_size = list(anchor_image_size) if anchor_image_size is not None else None + self.disable_custom_kernels = disable_custom_kernels + + self.class_thresholds = class_thresholds + self.class_order = class_order + + super().__init__(is_encoder_decoder=is_encoder_decoder, **kwargs) + + +class PPDocLayoutV2ImageProcessorFast(PPDocLayoutV3ImageProcessorFast): + def extract_custom_vertices(self): + raise AttributeError("Not needed for PPDocLayoutV2") + + def _mask2polygon(self): + raise AttributeError("Not needed for PPDocLayoutV2") + + def _extract_polygon_points_by_masks(self): + raise AttributeError("Not needed for PPDocLayoutV2") + + def post_process_object_detection( + self, + outputs, + threshold: float = 0.5, + target_sizes: TensorType | list[tuple] | None = None, + ): + """ + Converts the raw output of [`DetrForObjectDetection`] into final bounding boxes in (top_left_x, top_left_y, + bottom_right_x, bottom_right_y) format. Only supports PyTorch. + + PPDocLayoutV2 is identical to PPDocLayoutV3, except that it does not return `polygon_points`. + + Args: + outputs ([`DetrObjectDetectionOutput`]): + Raw outputs of the model. + Returns: + `list[Dict]`: A list of dictionaries, each dictionary containing the scores, labels and boxes for an image + in the batch as predicted by the model. + """ + boxes = outputs.pred_boxes + logits = outputs.logits + order_logits = outputs.order_logits + + order_seqs = self._get_order_seqs(order_logits) + + box_centers, box_dims = torch.split(boxes, 2, dim=-1) + top_left_coords = box_centers - 0.5 * box_dims + bottom_right_coords = box_centers + 0.5 * box_dims + boxes = torch.cat([top_left_coords, bottom_right_coords], dim=-1) + + if target_sizes is not None: + if len(logits) != len(target_sizes): + raise ValueError( + "Make sure that you pass in as many target sizes as the batch dimension of the logits" + ) + if isinstance(target_sizes, list): + img_height, img_width = torch.as_tensor(target_sizes).unbind(1) + else: + img_height, img_width = target_sizes.unbind(1) + scale_factor = torch.stack([img_width, img_height, img_width, img_height], dim=1).to(boxes.device) + boxes = boxes * scale_factor[:, None, :] + + num_top_queries = logits.shape[1] + num_classes = logits.shape[2] + + scores = torch.nn.functional.sigmoid(logits) + scores, index = torch.topk(scores.flatten(1), num_top_queries, dim=-1) + labels = index % num_classes + index = index // num_classes + boxes = boxes.gather(dim=1, index=index.unsqueeze(-1).repeat(1, 1, boxes.shape[-1])) + order_seqs = order_seqs.gather(dim=1, index=index) + + results = [] + for score, label, box, order_seq in zip(scores, labels, boxes, order_seqs): + order_seq = order_seq[score >= threshold] + order_seq, indices = torch.sort(order_seq) + results.append( + { + "scores": score[score >= threshold][indices], + "labels": label[score >= threshold][indices], + "boxes": box[score >= threshold][indices], + "order_seq": order_seq, + } + ) + + return results + + +class PPDocLayoutV2GlobalPointer(PPDocLayoutV3GlobalPointer): + def __init__(self, config): + super().__init__() + self.dense = nn.Linear(config.hidden_size, self.head_size * 2) + + +class PPDocLayoutV2PositionRelationEmbedding(nn.Module): + inv_freq: torch.Tensor + + def __init__(self, config, device=None): + super().__init__() + self.config = config + self.embed_dim = config.relation_bias_embed_dim + self.scale = config.relation_bias_scale + self.pos_proj = nn.Conv2d( + in_channels=self.embed_dim * 4, out_channels=config.num_attention_heads, kernel_size=1 + ) + inv_freq, self.attention_scaling = self.compute_default_rope_parameters(config, device) + self.register_buffer("inv_freq", inv_freq, persistent=False) + + @staticmethod + def compute_default_rope_parameters( + config: PPDocLayoutV2Config | None = None, + device: Optional["torch.device"] = None, + seq_len: int | None = None, + ) -> tuple["torch.Tensor", float]: + """ + Computes the inverse frequencies according to the original RoPE implementation + Args: + config ([`~transformers.PreTrainedConfig`]): + The model configuration. + device (`torch.device`): + The device to use for initialization of the inverse frequencies. + seq_len (`int`, *optional*): + The current sequence length. Unused for this type of RoPE. + Returns: + Tuple of (`torch.Tensor`, `float`), containing the inverse frequencies for the RoPE embeddings and the + post-processing scaling factor applied to the computed cos/sin (unused in this type of RoPE). + """ + base = config.relation_bias_theta + dim = config.relation_bias_embed_dim + half_dim = dim // 2 + + attention_factor = 1.0 # Unused in this type of RoPE + + # Compute the inverse frequencies + inv_freq = 1.0 / ( + base ** (torch.arange(0, dim, 2, dtype=torch.int64).to(device=device, dtype=torch.float) / half_dim) + ) + return inv_freq, attention_factor + + def box_relative_encoding( + self, source_boxes: torch.Tensor, target_boxes: torch.Tensor = None, epsilon: float = 1e-5 + ): + source_boxes, target_boxes = source_boxes.unsqueeze(-2), target_boxes.unsqueeze(-3) + source_coordinates, source_dim = source_boxes[..., :2], source_boxes[..., 2:] + target_coordinates, target_dim = target_boxes[..., :2], target_boxes[..., 2:] + + coordinate_difference = torch.abs(source_coordinates - target_coordinates) + relative_coordinates = torch.log(coordinate_difference / (source_dim + epsilon) + 1.0) + relative_dim = torch.log((source_dim + epsilon) / (target_dim + epsilon)) + + relative_encoding = torch.cat([relative_coordinates, relative_dim], dim=-1) + + return relative_encoding + + def get_position_embedding(self, x: torch.Tensor, scale: float = 100.0): + embedding = (x * scale).unsqueeze(-1) * self.inv_freq + embedding = torch.cat((embedding.sin(), embedding.cos()), dim=-1).flatten(start_dim=-2).to(x.dtype) + + return embedding + + def forward(self, source_boxes: torch.Tensor, target_boxes: torch.Tensor = None): + if target_boxes is None: + target_boxes = source_boxes + with torch.no_grad(): + relative_encoding = self.box_relative_encoding(source_boxes, target_boxes) + position_embedding = self.get_position_embedding(relative_encoding, self.scale) + position_embedding = position_embedding.permute(0, 3, 1, 2) + out = self.pos_proj(position_embedding) + return out + + +class PPDocLayoutV2ReadingOrderSelfAttention(LayoutLMv3SelfAttention): + def forward( + self, + hidden_states, + attention_mask=None, + output_attentions=False, + rel_pos=None, + rel_2d_pos=None, + ): + batch_size, seq_length, _ = hidden_states.shape + query_layer = ( + self.query(hidden_states) + .view(batch_size, -1, self.num_attention_heads, self.attention_head_size) + .transpose(1, 2) + ) + key_layer = ( + self.key(hidden_states) + .view(batch_size, -1, self.num_attention_heads, self.attention_head_size) + .transpose(1, 2) + ) + value_layer = ( + self.value(hidden_states) + .view(batch_size, -1, self.num_attention_heads, self.attention_head_size) + .transpose(1, 2) + ) + + # Take the dot product between "query" and "key" to get the raw attention scores. + # The attention scores QT K/√d could be significantly larger than input elements, and result in overflow. + # Changing the computational order into QT(K/√d) alleviates the problem. (https://huggingface.co/papers/2105.13290) + attention_scores = torch.matmul(query_layer / math.sqrt(self.attention_head_size), key_layer.transpose(-1, -2)) + + # NOTE: + # PPDocLayoutV2ReadingOrder applies unscaled rel_2d_pos + # unlike LayoutLMv3 which uses (rel_pos + rel_2d_pos) / math.sqrt(self.attention_head_size) + if rel_2d_pos is not None: + attention_scores += rel_2d_pos + elif self.has_relative_attention_bias: + attention_scores += rel_pos / math.sqrt(self.attention_head_size) + + if attention_mask is not None: + # Apply the attention mask is (precomputed for all layers in RobertaModel forward() function) + attention_scores = attention_scores + attention_mask + + # Normalize the attention scores to probabilities. + # Use the trick of the CogView paper to stabilize training + attention_probs = self.cogview_attention(attention_scores) + + # This is actually dropping out entire tokens to attend to, which might + # seem a bit unusual, but is taken from the original Transformer paper. + attention_probs = self.dropout(attention_probs) + + context_layer = torch.matmul(attention_probs, value_layer) + + context_layer = context_layer.permute(0, 2, 1, 3).contiguous() + new_context_layer_shape = context_layer.size()[:-2] + (self.all_head_size,) + context_layer = context_layer.view(*new_context_layer_shape) + + outputs = (context_layer, attention_probs) if output_attentions else (context_layer,) + + return outputs + + +class PPDocLayoutV2ReadingOrderSelfOutput(LayoutLMv3SelfOutput): + def __init__(self, config): + super().__init__() + del self.LayerNorm + self.norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps) + + def forward(self, hidden_states: torch.Tensor, input_tensor: torch.Tensor) -> torch.Tensor: + hidden_states = self.dense(hidden_states) + hidden_states = self.dropout(hidden_states) + hidden_states = self.norm(hidden_states + input_tensor) + return hidden_states + + +class PPDocLayoutV2ReadingOrderIntermediate(LayoutLMv3Intermediate): + pass + + +class PPDocLayoutV2ReadingOrderOutput(LayoutLMv3Output): + def __init__(self, config): + super().__init__() + del self.LayerNorm + self.norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps) + + def forward(self, hidden_states: torch.Tensor, input_tensor: torch.Tensor) -> torch.Tensor: + hidden_states = self.dense(hidden_states) + hidden_states = self.dropout(hidden_states) + hidden_states = self.norm(hidden_states + input_tensor) + return hidden_states + + +class PPDocLayoutV2ReadingOrderAttention(LayoutLMv3Attention): + def __init__(self, config): + super().__init__() + self.self = PPDocLayoutV2ReadingOrderSelfAttention(config) + self.output = PPDocLayoutV2ReadingOrderSelfOutput(config) + + +class PPDocLayoutV2ReadingOrderLayer(LayoutLMv3Layer): + def __init__(self, config): + super().__init__() + self.attention = PPDocLayoutV2ReadingOrderAttention(config) + self.intermediate = PPDocLayoutV2ReadingOrderIntermediate(config) + self.output = PPDocLayoutV2ReadingOrderOutput(config) + + +class PPDocLayoutV2ReadingOrderEncoder(LayoutLMv3Encoder): + def __init__(self, config): + super().__init__(config) + self.layer = nn.ModuleList([PPDocLayoutV2ReadingOrderLayer(config) for _ in range(config.num_hidden_layers)]) + self.rel_bias_module = PPDocLayoutV2PositionRelationEmbedding(config) + + def _cal_2d_pos_emb(self, bbox): + x_min, y_min, x_max, y_max = ( + bbox[..., 0], + bbox[..., 1], + bbox[..., 2], + bbox[..., 3], + ) + + width = (x_max - x_min).clamp(min=1e-3) + height = (y_max - y_min).clamp(min=1e-3) + + center_x = (x_min + x_max) * 0.5 + center_y = (y_min + y_max) * 0.5 + + center_width_height_bbox = torch.stack([center_x, center_y, width, height], dim=-1) + + result = self.rel_bias_module(center_width_height_bbox) + + return result + + +class PPDocLayoutV2TextEmbeddings(LayoutLMv3TextEmbeddings): + def __init__(self, config): + super().__init__(config) + + del self.LayerNorm + self.norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps) + spatial_embed_dim = 4 * config.coordinate_size + 2 * config.shape_size + self.spatial_proj = nn.Linear(spatial_embed_dim, config.hidden_size) + + def forward( + self, + input_ids=None, + bbox=None, + token_type_ids=None, + position_ids=None, + inputs_embeds=None, + ): + if position_ids is None: + if input_ids is not None: + # Create the position ids from the input token ids. Any padded tokens remain padded. + position_ids = self.create_position_ids_from_input_ids(input_ids, self.padding_idx).to( + input_ids.device + ) + else: + position_ids = self.create_position_ids_from_inputs_embeds(inputs_embeds) + + if input_ids is not None: + input_shape = input_ids.size() + else: + input_shape = inputs_embeds.size()[:-1] + + if token_type_ids is None: + token_type_ids = torch.zeros(input_shape, dtype=torch.long, device=self.position_ids.device) + + if inputs_embeds is None: + inputs_embeds = self.word_embeddings(input_ids) + + token_type_embeddings = self.token_type_embeddings(token_type_ids) + embeddings = inputs_embeds + token_type_embeddings + + position_embeddings = self.position_embeddings(position_ids) + embeddings += position_embeddings + + # custom new spatial embeddings + spatial_position_embeddings = self.calculate_spatial_position_embeddings(bbox) + spatial_position_embeddings = self.spatial_proj(spatial_position_embeddings) + embeddings += spatial_position_embeddings + return embeddings + + +@auto_docstring +class PPDocLayoutV2PreTrainedModel(RTDetrPreTrainedModel): + @torch.no_grad() + def _init_weights(self, module): + """Initialize the weights""" + super()._init_weights(module) + if isinstance(module, PPDocLayoutV2TextEmbeddings): + init.copy_(module.position_ids, torch.arange(module.position_ids.shape[-1]).expand((1, -1))) + if isinstance(module, nn.Embedding): + init.normal_(module.weight, mean=0.0, std=self.config.initializer_range) + if module.padding_idx is not None: + init.zeros_(module.weight.data[module.padding_idx]) + if isinstance(module, PPDocLayoutV2PositionRelationEmbedding): + inv_freq, _ = module.compute_default_rope_parameters(module.config, module.inv_freq.device) + module.register_buffer("inv_freq", inv_freq, persistent=False) + + +@auto_docstring( + custom_intro=""" + PP-DocLayoutV2 ReadingOrder Model. This model consists of an encoder and a GlobalPointer head. + It takes layout features as input and outputs logits representing the relative ordering relationships + between elements, which are used to determine the final reading sequence. + """ +) +class PPDocLayoutV2ReadingOrder(PPDocLayoutV2PreTrainedModel): + # Attention is based on LayoutLMv3 (no interface) + _supports_sdpa = False + _supports_flash_attn = False + _supports_attention_backend = False + _supports_flex_attn = False + + def __init__(self, config): + super().__init__(config) + self.embeddings = PPDocLayoutV2TextEmbeddings(config) + self.label_embeddings = nn.Embedding(config.num_classes, config.hidden_size) + self.label_features_projection = nn.Linear(config.hidden_size, config.hidden_size) + self.encoder = PPDocLayoutV2ReadingOrderEncoder(config) + self.relative_head = PPDocLayoutV2GlobalPointer(config) + self.config = config + + self.post_init() + + @auto_docstring + def forward(self, boxes, labels=None, mask=None, **kwargs: Unpack[TransformersKwargs]): + r""" + boxes (`torch.Tensor` of shape `(batch_size, sequence_length, 4)`): + Bounding box coordinates of the detected layout elements **in [0, 1000] scale**. + Format is `[x_min, y_min, x_max, y_max]`. + The tensor usually contains sorted valid boxes followed by zero-padding. + + labels (`torch.Tensor` of shape `(batch_size, sequence_length)`, *optional*): + The **remapped** class indices for each layout element. + These are not necessarily the raw detection class IDs, but indices mapped via + `config.class_order` (e.g., mapping text/title/figure to specific reading-order category IDs). + + mask (`torch.Tensor` of shape `(batch_size, sequence_length)`, *optional*): + Boolean or Binary mask indicating valid detected elements after threshold filtering. + - True: Valid layout element. + - False: Padding/Empty element. + Used to determine the sequence length (`num_pred`) for the pointer mechanism. + """ + device = mask.device + batch_size, seq_len = mask.shape + num_pred = mask.sum(dim=1) + + input_ids = torch.full( + (batch_size, seq_len + 2), self.config.pad_token_id, dtype=torch.long, device=boxes.device + ) + input_ids[:, 0] = self.config.start_token_id + + pred_col_idx = torch.arange(seq_len + 2, device=device).unsqueeze(0) + pred_mask = (pred_col_idx >= 1) & (pred_col_idx <= num_pred.unsqueeze(1)) + input_ids[pred_mask] = self.config.pred_token_id + end_col_indices = num_pred + 1 + input_ids[torch.arange(batch_size, device=device), end_col_indices] = self.config.end_token_id + + pad_box = torch.zeros(size=[boxes.shape[0], 1, boxes.shape[-1]], dtype=boxes.dtype, device=boxes.device) + pad_boxes = torch.cat([pad_box, boxes, pad_box], dim=1) + bbox_embedding = self.embeddings(input_ids=input_ids, bbox=pad_boxes.long()) + + if labels is not None: + label_embs = self.label_embeddings(labels) + label_proj = self.label_features_projection(label_embs) + pad = torch.zeros( + size=[label_proj.shape[0], 1, label_proj.shape[-1]], dtype=label_proj.dtype, device=labels.device + ) + label_proj = torch.cat([pad, label_proj, pad], dim=1) + else: + label_proj = torch.zeros_like(bbox_embedding) + + final_embeddings = bbox_embedding + label_proj + final_embeddings = self.embeddings.norm(final_embeddings) + final_embeddings = self.embeddings.dropout(final_embeddings) + + attention_mask = pred_col_idx < (num_pred + 2).unsqueeze(1) + attention_mask = create_bidirectional_mask( + config=self.config, + inputs_embeds=final_embeddings, + attention_mask=attention_mask, + ) + encoder_output = self.encoder(hidden_states=final_embeddings, bbox=pad_boxes, attention_mask=attention_mask) + encoder_output = encoder_output.last_hidden_state + token = encoder_output[:, 1 : 1 + seq_len, :] + read_order_logits = self.relative_head(token) + return read_order_logits + + +@dataclass +@auto_docstring +class PPDocLayoutV2ForObjectDetectionOutput(ModelOutput): + r""" + logits (`torch.FloatTensor` of shape `(batch_size, num_queries, num_classes + 1)`): + Classification logits (including no-object) for all queries. + order_logits (`tuple` of `torch.FloatTensor` of shape `(batch_size, num_queries, num_queries)`): + Order logits for all queries. The first dimension of each tensor is the batch size. The second dimension is the number of queries. + pred_boxes (`torch.FloatTensor` of shape `(batch_size, num_queries, 4)`): + Normalized boxes coordinates for all queries, represented as (center_x, center_y, width, height). These + values are normalized in [0, 1], relative to the size of each individual image in the batch (disregarding + possible padding). You can use [`~RTDetrImageProcessor.post_process_object_detection`] to retrieve the + unnormalized (absolute) bounding boxes. + last_hidden_state (`torch.FloatTensor` of shape `(batch_size, num_queries, hidden_size)`): + Sequence of hidden-states at the output of the last layer of the decoder of the model. + intermediate_hidden_states (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, hidden_size)`): + Stacked intermediate hidden states (output of each layer of the decoder). + intermediate_logits (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, config.num_labels)`): + Stacked intermediate logits (logits of each layer of the decoder). + intermediate_reference_points (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, 4)`): + Stacked intermediate reference points (reference points of each layer of the decoder). + intermediate_predicted_corners (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, 4)`): + Stacked intermediate predicted corners (predicted corners of each layer of the decoder). + initial_reference_points (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, 4)`): + Stacked initial reference points (initial reference points of each layer of the decoder). + init_reference_points (`torch.FloatTensor` of shape `(batch_size, num_queries, 4)`): + Initial reference points sent through the Transformer decoder. + enc_topk_logits (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.num_labels)`, *optional*, returned when `config.with_box_refine=True` and `config.two_stage=True`): + Logits of predicted bounding boxes coordinates in the encoder. + enc_topk_bboxes (`torch.FloatTensor` of shape `(batch_size, sequence_length, 4)`, *optional*, returned when `config.with_box_refine=True` and `config.two_stage=True`): + Logits of predicted bounding boxes coordinates in the encoder. + enc_outputs_class (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.num_labels)`, *optional*, returned when `config.with_box_refine=True` and `config.two_stage=True`): + Predicted bounding boxes scores where the top `config.two_stage_num_proposals` scoring bounding boxes are + picked as region proposals in the first stage. Output of bounding box binary classification (i.e. + foreground and background). + enc_outputs_coord_logits (`torch.FloatTensor` of shape `(batch_size, sequence_length, 4)`, *optional*, returned when `config.with_box_refine=True` and `config.two_stage=True`): + Logits of predicted bounding boxes coordinates in the first stage. + denoising_meta_values (`dict`): + Extra dictionary for the denoising related values + """ + + logits: torch.FloatTensor | None = None + pred_boxes: torch.FloatTensor | None = None + order_logits: tuple[torch.FloatTensor] | None = None + last_hidden_state: torch.FloatTensor | None = None + intermediate_hidden_states: torch.FloatTensor | None = None + intermediate_logits: torch.FloatTensor | None = None + intermediate_reference_points: torch.FloatTensor | None = None + intermediate_predicted_corners: torch.FloatTensor | None = None + initial_reference_points: torch.FloatTensor | None = None + decoder_hidden_states: tuple[torch.FloatTensor] | None = None + decoder_attentions: tuple[torch.FloatTensor] | None = None + cross_attentions: tuple[torch.FloatTensor] | None = None + encoder_last_hidden_state: torch.FloatTensor | None = None + encoder_hidden_states: tuple[torch.FloatTensor] | None = None + encoder_attentions: tuple[torch.FloatTensor] | None = None + init_reference_points: tuple[torch.FloatTensor] | None = None + enc_topk_logits: torch.FloatTensor | None = None + enc_topk_bboxes: torch.FloatTensor | None = None + enc_outputs_class: torch.FloatTensor | None = None + enc_outputs_coord_logits: torch.FloatTensor | None = None + denoising_meta_values: dict | None = None + + +@dataclass +@auto_docstring( + custom_intro=""" + Base class for outputs of the PP-DocLayoutV2 encoder-decoder model. + """ +) +class PPDocLayoutV2ModelOutput(RTDetrModelOutput): + pass + + +class PPDocLayoutV2MLPPredictionHead(RTDetrMLPPredictionHead): + pass + + +@auto_docstring( + custom_intro=""" + PP-DocLayoutV2 Model (consisting of a backbone and encoder-decoder) outputting raw hidden states without any head on top. + """ +) +class PPDocLayoutV2Model(RTDetrModel): + def __init__(self, config: PPDocLayoutV2Config): + super().__init__() + self.denoising_class_embed = nn.Embedding(config.num_labels, config.d_model) + + +@auto_docstring( + custom_intro=""" + PP-DocLayoutV2 Model (consisting of a backbone and encoder-decoder) outputting bounding boxes, logits and order_logits to be further + decoded into scores, classes and their reading order. + """ +) +class PPDocLayoutV2ForObjectDetection(RTDetrForObjectDetection): + _keys_to_ignore_on_load_missing = ["num_batches_tracked", "rel_pos_y_bias", "rel_pos_x_bias"] + + def __init__(self, config: PPDocLayoutV2Config): + super().__init__(config) + + self.reading_order = PPDocLayoutV2ReadingOrder(config.reading_order_config) + self.num_queries = config.num_queries + self.config = config + + self.post_init() + + @auto_docstring + @can_return_tuple + def forward( + self, + pixel_values: torch.FloatTensor, + pixel_mask: torch.LongTensor | None = None, + encoder_outputs: torch.FloatTensor | None = None, + inputs_embeds: torch.FloatTensor | None = None, + decoder_inputs_embeds: torch.FloatTensor | None = None, + labels: list[dict] | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.FloatTensor] | PPDocLayoutV2ForObjectDetectionOutput: + r""" + inputs_embeds (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*): + Optionally, instead of passing the flattened feature map (output of the backbone + projection layer), you + can choose to directly pass a flattened representation of an image. + decoder_inputs_embeds (`torch.FloatTensor` of shape `(batch_size, num_queries, hidden_size)`, *optional*): + Optionally, instead of initializing the queries with a tensor of zeros, you can choose to directly pass an + embedded representation. + labels (`list[Dict]` of len `(batch_size,)`, *optional*): + Labels for computing the bipartite matching loss. List of dicts, each dictionary containing at least the + following 2 keys: 'class_labels' and 'boxes' (the class labels and bounding boxes of an image in the batch + respectively). The class labels themselves should be a `torch.LongTensor` of len `(number of bounding boxes + in the image,)` and the boxes a `torch.FloatTensor` of shape `(number of bounding boxes in the image, 4)`. + + Examples: + + ```python + >>> from transformers import AutoModelForObjectDetection, AutoImageProcessor + >>> from PIL import Image + >>> import requests + >>> import torch + + >>> url = "https://paddle-model-ecology.bj.bcebos.com/paddlex/imgs/demo_image/layout_demo.jpg" + >>> image = Image.open(requests.get(url, stream=True).raw) + + >>> model_path = "PaddlePaddle/PP-DocLayoutV2_safetensors" + >>> image_processor = AutoImageProcessor.from_pretrained(model_path) + >>> model = AutoModelForObjectDetection.from_pretrained(model_path) + + >>> # prepare image for the model + >>> inputs = image_processor(images=[image], return_tensors="pt") + + >>> # forward pass + >>> outputs = model(**inputs) + + >>> # convert outputs (bounding boxes and class logits) to Pascal VOC format (xmin, ymin, xmax, ymax) + >>> results = image_processor.post_process_object_detection(outputs, target_sizes=torch.tensor([image.size[::-1]])) + + >>> # print outputs + >>> for result in results: + ... for idx, (score, label_id, box) in enumerate(zip(result["scores"], result["labels"], result["boxes"])): + ... score, label = score.item(), label_id.item() + ... box = [round(i, 2) for i in box.tolist()] + ... print(f"Order {idx + 1}: {model.config.id2label[label]}: {score:.2f} {box}") + Order 1: text: 0.99 [335.39, 184.26, 896.49, 654.48] + Order 2: paragraph_title: 0.97 [337.14, 683.49, 869.42, 798.27] + Order 3: text: 0.99 [335.71, 843.04, 891.17, 1454.15] + Order 4: text: 0.99 [920.42, 185.53, 1476.39, 464.25] + Order 5: text: 0.98 [920.62, 483.75, 1480.52, 765.34] + Order 6: text: 0.98 [920.58, 846.75, 1481.94, 1220.53] + Order 7: text: 0.97 [921.12, 1239.27, 1468.87, 1377.33] + Order 8: footnote: 0.82 [334.58, 1614.67, 1483.84, 1731.61] + Order 9: text: 0.51 [334.58, 1614.67, 1483.84, 1731.61] + Order 10: footnote: 0.83 [334.7, 1757.26, 1471.07, 1845.33] + Order 11: text: 0.87 [336.65, 1910.28, 661.33, 1939.92] + Order 12: footnote: 0.95 [336.16, 2114.52, 1450.28, 2171.74] + Order 13: number: 0.87 [106.04, 2257.37, 136.05, 2281.98] + Order 14: footer: 0.93 [338.6, 2255.94, 985.67, 2283.57] + ```""" + outputs = self.model( + pixel_values, + pixel_mask=pixel_mask, + encoder_outputs=encoder_outputs, + inputs_embeds=inputs_embeds, + decoder_inputs_embeds=decoder_inputs_embeds, + labels=labels, + **kwargs, + ) + + intermediate_reference_points = outputs.intermediate_reference_points + intermediate_logits = outputs.intermediate_logits + raw_bboxes = intermediate_reference_points[:, -1] + logits = intermediate_logits[:, -1] + + box_centers, box_sizes = raw_bboxes.split(2, dim=-1) + bboxes = torch.cat([box_centers - 0.5 * box_sizes, box_centers + 0.5 * box_sizes], dim=-1) * 1000 + bboxes = bboxes.clamp_(0.0, 1000.0) + + max_logits, class_ids = logits.max(dim=-1) + max_probs = max_logits.sigmoid() + + class_thresholds = torch.tensor(self.config.class_thresholds, dtype=torch.float32, device=logits.device) + thresholds = class_thresholds[class_ids] + mask = max_probs >= thresholds + + indices = torch.argsort(mask.to(torch.int8), dim=1, descending=True) + + sorted_class_ids = torch.take_along_dim(class_ids, indices, dim=1) + sorted_boxes = torch.take_along_dim(bboxes, indices[..., None].expand(-1, -1, 4), dim=1) + pred_boxes = torch.take_along_dim(raw_bboxes, indices[..., None].expand(-1, -1, 4), dim=1) + logits = torch.take_along_dim(logits, indices[..., None].expand(-1, -1, logits.size(-1)), dim=1) + + sorted_mask = torch.take_along_dim(mask, indices, dim=1) + + pad_boxes = torch.where(sorted_mask[..., None], sorted_boxes, torch.zeros_like(sorted_boxes)) + pad_class_ids = torch.where(sorted_mask, sorted_class_ids, torch.zeros_like(sorted_class_ids)) + + class_order = torch.tensor(self.config.class_order, dtype=torch.int32, device=logits.device) + pad_class_ids = class_order[pad_class_ids] + + order_logits = self.reading_order( + boxes=pad_boxes, + labels=pad_class_ids, + mask=mask, + ) + order_logits = order_logits[:, :, : self.num_queries] + + if labels is not None: + raise ValueError("PPDocLayoutV2ForObjectDetection does not support training") + + return PPDocLayoutV2ForObjectDetectionOutput( + logits=logits, + pred_boxes=pred_boxes, + order_logits=order_logits, + last_hidden_state=outputs.last_hidden_state, + intermediate_hidden_states=outputs.intermediate_hidden_states, + intermediate_logits=outputs.intermediate_logits, + intermediate_reference_points=outputs.intermediate_reference_points, + intermediate_predicted_corners=outputs.intermediate_predicted_corners, + initial_reference_points=outputs.initial_reference_points, + decoder_hidden_states=outputs.decoder_hidden_states, + decoder_attentions=outputs.decoder_attentions, + cross_attentions=outputs.cross_attentions, + encoder_last_hidden_state=outputs.encoder_last_hidden_state, + encoder_hidden_states=outputs.encoder_hidden_states, + encoder_attentions=outputs.encoder_attentions, + init_reference_points=outputs.init_reference_points, + enc_topk_logits=outputs.enc_topk_logits, + enc_topk_bboxes=outputs.enc_topk_bboxes, + enc_outputs_class=outputs.enc_outputs_class, + enc_outputs_coord_logits=outputs.enc_outputs_coord_logits, + denoising_meta_values=outputs.denoising_meta_values, + ) + + +__all__ = [ + "PPDocLayoutV2ForObjectDetection", + "PPDocLayoutV2ImageProcessorFast", + "PPDocLayoutV2Config", + "PPDocLayoutV2Model", + "PPDocLayoutV2PreTrainedModel", + "PPDocLayoutV2ReadingOrder", +] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pp_doclayout_v3/__init__.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pp_doclayout_v3/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..55281a5ad722290e8d747d9fd0277dcb4f858c21 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pp_doclayout_v3/__init__.py @@ -0,0 +1,30 @@ +# Copyright 2026 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + + +from typing import TYPE_CHECKING + +from ...utils import _LazyModule +from ...utils.import_utils import define_import_structure + + +if TYPE_CHECKING: + from .configuration_pp_doclayout_v3 import * + from .image_processing_pp_doclayout_v3_fast import * + from .modeling_pp_doclayout_v3 import * +else: + import sys + + _file = globals()["__file__"] + sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__) diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pp_doclayout_v3/configuration_pp_doclayout_v3.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pp_doclayout_v3/configuration_pp_doclayout_v3.py new file mode 100644 index 0000000000000000000000000000000000000000..19d2b5be3777f9843d939a676cd0bbebd9a31f5c --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pp_doclayout_v3/configuration_pp_doclayout_v3.py @@ -0,0 +1,277 @@ +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# This file was automatically generated from src/transformers/models/pp_doclayout_v3/modular_pp_doclayout_v3.py. +# Do NOT edit this file manually as any edits will be overwritten by the generation of +# the file from the modular. If any change should be done, please apply the change to the +# modular_pp_doclayout_v3.py file directly. One of our CI enforces this. +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# Copyright 2026 The PaddlePaddle Team and The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +from ...backbone_utils import consolidate_backbone_kwargs_to_config +from ...configuration_utils import PreTrainedConfig +from ..auto import AutoConfig + + +class PPDocLayoutV3Config(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`PP-DocLayoutV3`]. It is used to instantiate a + PP-DocLayoutV3 model according to the specified arguments, defining the model architecture. Instantiating a configuration + with the defaults will yield a similar configuration to that of the PP-DocLayoutV3 + [PaddlePaddle/PP-DocLayoutV3_safetensors](https://huggingface.co/PaddlePaddle/PP-DocLayoutV3_safetensors) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + initializer_range (`float`, *optional*, defaults to 0.01): + The standard deviation of the truncated_normal_initializer for initializing all weight matrices. + initializer_bias_prior_prob (`float`, *optional*): + The prior probability used by the bias initializer to initialize biases for `enc_score_head` and `class_embed`. + If `None`, `prior_prob` computed as `prior_prob = 1 / (num_labels + 1)` while initializing model weights. + layer_norm_eps (`float`, *optional*, defaults to 1e-05): + The epsilon used by the layer normalization layers. + batch_norm_eps (`float`, *optional*, defaults to 1e-05): + The epsilon used by the batch normalization layers. + tie_word_embeddings (`bool`, *optional*, defaults to `True`): + Whether the model's input and output word embeddings should be tied. + backbone_config (`Union[dict, "PreTrainedConfig"]`, *optional*): + The configuration of the backbone model. + freeze_backbone_batch_norms (`bool`, *optional*, defaults to `True`): + Whether to freeze the batch normalization layers in the backbone. + encoder_hidden_dim (`int`, *optional*, defaults to 256): + Dimension of the layers in hybrid encoder. + encoder_in_channels (`list`, *optional*, defaults to `[512, 1024, 2048]`): + Multi level features input for encoder. + feat_strides (`list[int]`, *optional*, defaults to `[8, 16, 32]`): + Strides used in each feature map. + encoder_layers (`int`, *optional*, defaults to 1): + Total of layers to be used by the encoder. + encoder_ffn_dim (`int`, *optional*, defaults to 1024): + Dimension of the "intermediate" (often named feed-forward) layer in decoder. + encoder_attention_heads (`int`, *optional*, defaults to 8): + Number of attention heads for each attention layer in the Transformer encoder. + dropout (`float`, *optional*, defaults to 0.0): + The ratio for all dropout layers. + activation_dropout (`float`, *optional*, defaults to 0.0): + The dropout ratio for activations inside the fully connected layer. + encode_proj_layers (`list[int]`, *optional*, defaults to `[2]`): + Indexes of the projected layers to be used in the encoder. + positional_encoding_temperature (`int`, *optional*, defaults to 10000): + The temperature parameter used to create the positional encodings. + encoder_activation_function (`str`, *optional*, defaults to `"gelu"`): + The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`, + `"relu"`, `"silu"` and `"gelu_new"` are supported. + activation_function (`str`, *optional*, defaults to `"silu"`): + The non-linear activation function (function or string) in the general layer. If string, `"gelu"`, + `"relu"`, `"silu"` and `"gelu_new"` are supported. + eval_size (`tuple[int, int]`, *optional*): + Height and width used to computes the effective height and width of the position embeddings after taking + into account the stride. + normalize_before (`bool`, *optional*, defaults to `False`): + Determine whether to apply layer normalization in the transformer encoder layer before self-attention and + feed-forward modules. + hidden_expansion (`float`, *optional*, defaults to 1.0): + Expansion ratio to enlarge the dimension size of RepVGGBlock and CSPRepLayer. + mask_feature_channels (`list[int]`, *optional*, defaults to `[64, 64]`): + The channels of the multi-level features for mask enhancement. + x4_feat_dim (`int`, *optional*, defaults to 128): + The dimension of the x4 feature map. + d_model (`int`, *optional*, defaults to 256): + Dimension of the layers exclude hybrid encoder. + num_prototypes (`int`, *optional*, defaults to 32): + Dimension of the layers exclude mask query head. + label_noise_ratio (`float`, *optional*, defaults to 0.4): + The fraction of denoising labels to which random noise should be added. + box_noise_scale (`float`, *optional*, defaults to 0.4): + Scale or magnitude of noise to be added to the bounding boxes. + mask_enhanced (`bool`, *optional*, defaults to `True`): + Whether to use enhanced masked attention. + num_queries (`int`, *optional*, defaults to 300): + Number of object queries. + decoder_in_channels (`list`, *optional*, defaults to `[256, 256, 256]`): + Multi level features dimension for decoder + decoder_ffn_dim (`int`, *optional*, defaults to 1024): + Dimension of the "intermediate" (often named feed-forward) layer in decoder. + num_feature_levels (`int`, *optional*, defaults to 3): + The number of input feature levels. + decoder_n_points (`int`, *optional*, defaults to 4): + The number of sampled keys in each feature level for each attention head in the decoder. + decoder_layers (`int`, *optional*, defaults to 6): + Number of decoder layers. + decoder_attention_heads (`int`, *optional*, defaults to 8): + Number of attention heads for each attention layer in the Transformer decoder. + decoder_activation_function (`str`, *optional*, defaults to `"relu"`): + The non-linear activation function (function or string) in the decoder. If string, `"gelu"`, + `"relu"`, `"silu"` and `"gelu_new"` are supported. + attention_dropout (`float`, *optional*, defaults to 0.0): + The dropout ratio for the attention probabilities. + num_denoising (`int`, *optional*, defaults to 100): + The total number of denoising tasks or queries to be used for contrastive denoising. + learn_initial_query (`bool`, *optional*, defaults to `False`): + Indicates whether the initial query embeddings for the decoder should be learned during training + anchor_image_size (`tuple[int, int]`, *optional*): + Height and width of the input image used during evaluation to generate the bounding box anchors. If None, automatic generate anchor is applied. + disable_custom_kernels (`bool`, *optional*, defaults to `True`): + Whether to disable custom kernels. + is_encoder_decoder (`bool`, *optional*, defaults to `True`): + Whether the architecture has an encoder decoder structure. + global_pointer_head_size (`int`, *optional*, defaults to 64): + The size of the global pointer head. + gp_dropout_value (`float`, *optional*, defaults to 0.1): + The dropout probability in the global pointer head. + Examples: + + ```python + >>> from transformers import PPDocLayoutV3Config, PPDocLayoutV3ForObjectDetection + + >>> # Initializing a PP-DocLayoutV3 configuration + >>> configuration = PPDocLayoutV3Config() + + >>> # Initializing a model (with random weights) from the configuration + >>> model = PPDocLayoutV3ForObjectDetection(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "pp_doclayout_v3" + sub_configs = {"backbone_config": AutoConfig} + + layer_types = ("basic", "bottleneck") + attribute_map = { + "hidden_size": "d_model", + "num_attention_heads": "encoder_attention_heads", + } + + def __init__( + self, + initializer_range=0.01, + initializer_bias_prior_prob=None, + layer_norm_eps=1e-5, + batch_norm_eps=1e-5, + tie_word_embeddings=True, + # backbone + backbone_config=None, + freeze_backbone_batch_norms=True, + # encoder PPDocLayoutV3HybridEncoder + encoder_hidden_dim=256, + encoder_in_channels=[512, 1024, 2048], + feat_strides=[8, 16, 32], + encoder_layers=1, + encoder_ffn_dim=1024, + encoder_attention_heads=8, + dropout=0.0, + activation_dropout=0.0, + encode_proj_layers=[2], + positional_encoding_temperature=10000, + encoder_activation_function="gelu", + activation_function="silu", + eval_size=None, + normalize_before=False, + hidden_expansion=1.0, + mask_feature_channels=[64, 64], + x4_feat_dim=128, + # decoder PPDocLayoutV3Transformer + d_model=256, + num_prototypes=32, + label_noise_ratio=0.4, + box_noise_scale=0.4, + mask_enhanced=True, + num_queries=300, + decoder_in_channels=[256, 256, 256], + decoder_ffn_dim=1024, + num_feature_levels=3, + decoder_n_points=4, + decoder_layers=6, + decoder_attention_heads=8, + decoder_activation_function="relu", + attention_dropout=0.0, + num_denoising=100, + learn_initial_query=False, + anchor_image_size=None, + disable_custom_kernels=True, + is_encoder_decoder=True, + global_pointer_head_size=64, + gp_dropout_value=0.1, + **kwargs, + ): + self.initializer_range = initializer_range + self.initializer_bias_prior_prob = initializer_bias_prior_prob + self.layer_norm_eps = layer_norm_eps + self.batch_norm_eps = batch_norm_eps + self.tie_word_embeddings = tie_word_embeddings + + backbone_config, kwargs = consolidate_backbone_kwargs_to_config( + backbone_config=backbone_config, + default_config_type="hgnet_v2", + default_config_kwargs={ + "arch": "L", + "return_idx": [0, 1, 2, 3], + "freeze_stem_only": True, + "freeze_at": 0, + "freeze_norm": True, + "lr_mult_list": [0, 0.05, 0.05, 0.05, 0.05], + "out_features": ["stage1", "stage2", "stage3", "stage4"], + }, + **kwargs, + ) + + self.backbone_config = backbone_config + self.freeze_backbone_batch_norms = freeze_backbone_batch_norms + + # ---- encoder ---- + self.encoder_hidden_dim = encoder_hidden_dim + self.encoder_in_channels = list(encoder_in_channels) + self.feat_strides = list(feat_strides) + self.encoder_layers = encoder_layers + self.encoder_ffn_dim = encoder_ffn_dim + self.encoder_attention_heads = encoder_attention_heads + self.dropout = dropout + self.activation_dropout = activation_dropout + self.encode_proj_layers = list(encode_proj_layers) + self.positional_encoding_temperature = positional_encoding_temperature + self.encoder_activation_function = encoder_activation_function + self.activation_function = activation_function + self.eval_size = list(eval_size) if eval_size is not None else None + self.normalize_before = normalize_before + self.hidden_expansion = hidden_expansion + self.mask_feature_channels = mask_feature_channels + self.x4_feat_dim = x4_feat_dim + + # ---- decoder ---- + self.d_model = d_model + self.num_queries = num_queries + self.num_prototypes = num_prototypes + self.decoder_in_channels = list(decoder_in_channels) + self.decoder_ffn_dim = decoder_ffn_dim + self.num_feature_levels = num_feature_levels + self.decoder_n_points = decoder_n_points + self.decoder_layers = decoder_layers + self.decoder_attention_heads = decoder_attention_heads + self.decoder_activation_function = decoder_activation_function + self.attention_dropout = attention_dropout + self.num_denoising = num_denoising + self.label_noise_ratio = label_noise_ratio + self.mask_enhanced = mask_enhanced + self.box_noise_scale = box_noise_scale + self.learn_initial_query = learn_initial_query + self.anchor_image_size = list(anchor_image_size) if anchor_image_size is not None else None + self.disable_custom_kernels = disable_custom_kernels + self.global_pointer_head_size = global_pointer_head_size + self.gp_dropout_value = gp_dropout_value + + super().__init__(is_encoder_decoder=is_encoder_decoder, **kwargs) + + +__all__ = ["PPDocLayoutV3Config"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pp_doclayout_v3/image_processing_pp_doclayout_v3_fast.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pp_doclayout_v3/image_processing_pp_doclayout_v3_fast.py new file mode 100644 index 0000000000000000000000000000000000000000..b220ab41034424af0dd39d0584d7b4f890ab7e84 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pp_doclayout_v3/image_processing_pp_doclayout_v3_fast.py @@ -0,0 +1,302 @@ +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# This file was automatically generated from src/transformers/models/pp_doclayout_v3/modular_pp_doclayout_v3.py. +# Do NOT edit this file manually as any edits will be overwritten by the generation of +# the file from the modular. If any change should be done, please apply the change to the +# modular_pp_doclayout_v3.py file directly. One of our CI enforces this. +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# Copyright 2026 The PaddlePaddle Team and The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +from typing import Optional + +import numpy as np +import torch +import torchvision.transforms.v2.functional as tvF + +from ...image_processing_utils_fast import BaseImageProcessorFast, BatchFeature +from ...image_transforms import group_images_by_shape, reorder_images +from ...image_utils import PILImageResampling, SizeDict +from ...utils import auto_docstring, is_cv2_available, requires_backends +from ...utils.generic import TensorType + + +if is_cv2_available(): + import cv2 + + +@auto_docstring +class PPDocLayoutV3ImageProcessorFast(BaseImageProcessorFast): + resample = PILImageResampling.BICUBIC + image_mean = [0, 0, 0] + image_std = [1, 1, 1] + size = {"height": 800, "width": 800} + do_resize = True + do_rescale = True + do_normalize = True + + # We require `self.resize(..., antialias=False)` to approximate the output of `cv2.resize` + def _preprocess( + self, + images: list["torch.Tensor"], + do_resize: bool, + size: SizeDict, + interpolation: Optional["tvF.InterpolationMode"], + do_center_crop: bool, + crop_size: SizeDict, + do_rescale: bool, + rescale_factor: float, + do_normalize: bool, + image_mean: float | list[float] | None, + image_std: float | list[float] | None, + do_pad: bool | None, + pad_size: SizeDict | None, + disable_grouping: bool | None, + return_tensors: str | TensorType | None, + **kwargs, + ) -> BatchFeature: + # Group images by size for batched resizing + grouped_images, grouped_images_index = group_images_by_shape(images, disable_grouping=disable_grouping) + resized_images_grouped = {} + for shape, stacked_images in grouped_images.items(): + if do_resize: + stacked_images = self.resize( + image=stacked_images, size=size, interpolation=interpolation, antialias=False + ) + resized_images_grouped[shape] = stacked_images + resized_images = reorder_images(resized_images_grouped, grouped_images_index) + + # Group images by size for further processing + # Needed in case do_resize is False, or resize returns images with different sizes + grouped_images, grouped_images_index = group_images_by_shape(resized_images, disable_grouping=disable_grouping) + processed_images_grouped = {} + for shape, stacked_images in grouped_images.items(): + if do_center_crop: + stacked_images = self.center_crop(stacked_images, crop_size) + # Fused rescale and normalize + stacked_images = self.rescale_and_normalize( + stacked_images, do_rescale, rescale_factor, do_normalize, image_mean, image_std + ) + processed_images_grouped[shape] = stacked_images + processed_images = reorder_images(processed_images_grouped, grouped_images_index) + + if do_pad: + processed_images = self.pad(processed_images, pad_size=pad_size, disable_grouping=disable_grouping) + + return BatchFeature(data={"pixel_values": processed_images}, tensor_type=return_tensors) + + def _get_order_seqs(self, order_logits): + """ + Computes the order sequences for a batch of inputs based on logits. + + This function takes in the order logits, calculates order scores using a sigmoid activation, + and determines the order sequences by ranking the votes derived from the scores. + + Args: + order_logits (`torch.FloatTensor` of shape `(batch_size, num_queries, num_queries)`): + Stacked order logits. + + Returns: + torch.Tensor: A tensor of shape `(batch_size, num_queries)`: + Containing the computed order sequences for each input in the batch. Each row represents the ranked order of elements for the corresponding input in the batch. + """ + order_scores = torch.sigmoid(order_logits) + batch_size, sequence_length, _ = order_scores.shape + + order_votes = order_scores.triu(diagonal=1).sum(dim=1) + (1.0 - order_scores.transpose(1, 2)).tril( + diagonal=-1 + ).sum(dim=1) + + order_pointers = torch.argsort(order_votes, dim=1) + order_seq = torch.empty_like(order_pointers) + ranks = torch.arange(sequence_length, device=order_pointers.device, dtype=order_pointers.dtype).expand( + batch_size, -1 + ) + order_seq.scatter_(1, order_pointers, ranks) + + return order_seq + + def extract_custom_vertices(self, polygon, sharp_angle_thresh=45): + poly = np.array(polygon) + n = len(poly) + res = [] + i = 0 + while i < n: + previous_point = poly[(i - 1) % n] + current_point = poly[i] + next_point = poly[(i + 1) % n] + vector_1 = previous_point - current_point + vector_2 = next_point - current_point + cross_product_value = (vector_1[1] * vector_2[0]) - (vector_1[0] * vector_2[1]) + if cross_product_value < 0: + angle_cos = np.clip( + (vector_1 @ vector_2) / (np.linalg.norm(vector_1) * np.linalg.norm(vector_2)), -1.0, 1.0 + ) + angle = np.degrees(np.arccos(angle_cos)) + if abs(angle - sharp_angle_thresh) < 1: + # Calculate the new point based on the direction of two vectors. + dir_vec = vector_1 / np.linalg.norm(vector_1) + vector_2 / np.linalg.norm(vector_2) + dir_vec = dir_vec / np.linalg.norm(dir_vec) + step_size = (np.linalg.norm(vector_1) + np.linalg.norm(vector_2)) / 2 + new_point = current_point + dir_vec * step_size + res.append(tuple(new_point)) + else: + res.append(tuple(current_point)) + i += 1 + return res + + def _mask2polygon(self, mask, epsilon_ratio=0.004): + """ + Postprocess mask by removing small noise. + Args: + mask (ndarray): The input mask of shape [H, W]. + epsilon_ratio (float): The ratio of epsilon. + Returns: + ndarray: The output mask after postprocessing. + """ + contours, _ = cv2.findContours(mask, cv2.RETR_EXTERNAL, cv2.CHAIN_APPROX_SIMPLE) + + if not contours: + return None + + contours = max(contours, key=cv2.contourArea) + epsilon = epsilon_ratio * cv2.arcLength(contours, True) + approx_contours = cv2.approxPolyDP(contours, epsilon, True) + polygon_points = approx_contours.squeeze() + polygon_points = np.atleast_2d(polygon_points) + + polygon_points = self.extract_custom_vertices(polygon_points) + + return polygon_points + + def _extract_polygon_points_by_masks(self, boxes, masks, scale_ratio): + scale_width, scale_height = scale_ratio[0] / 4, scale_ratio[1] / 4 + mask_height, mask_width = masks.shape[1:] + polygon_points = [] + + for i in range(len(boxes)): + x_min, y_min, x_max, y_max = boxes[i].astype(np.int32) + box_w, box_h = x_max - x_min, y_max - y_min + + # default rect + rect = np.array( + [[x_min, y_min], [x_max, y_min], [x_max, y_max], [x_min, y_max]], + dtype=np.float32, + ) + + if box_w <= 0 or box_h <= 0: + polygon_points.append(rect) + continue + + # crop mask + x_coordinates = [int(round((x_min * scale_width).item())), int(round((x_max * scale_width).item()))] + x_start, x_end = np.clip(x_coordinates, 0, mask_width) + y_coordinates = [int(round((y_min * scale_height).item())), int(round((y_max * scale_height).item()))] + y_start, y_end = np.clip(y_coordinates, 0, mask_height) + cropped_mask = masks[i, y_start:y_end, x_start:x_end] + + # resize mask to match box size + resized_mask = cv2.resize(cropped_mask.astype(np.uint8), (box_w, box_h), interpolation=cv2.INTER_NEAREST) + + polygon = self._mask2polygon(resized_mask) + if polygon is not None and len(polygon) < 4: + polygon_points.append(rect) + continue + if polygon is not None and len(polygon) > 0: + polygon = polygon + np.array([x_min, y_min]) + + polygon_points.append(polygon) + + return polygon_points + + def post_process_object_detection( + self, + outputs, + threshold: float = 0.5, + target_sizes: TensorType | list[tuple] | None = None, + ): + """ + Converts the raw output of [`PPDocLayoutV3ForObjectDetection`] into final bounding boxes in (top_left_x, top_left_y, + bottom_right_x, bottom_right_y) format. Only supports PyTorch. + + Args: + outputs ([`DetrObjectDetectionOutput`]): + Raw outputs of the model. + Returns: + `list[Dict]`: A list of dictionaries, each dictionary containing the scores, labels, boxes and polygon_points for an image + in the batch as predicted by the model. + """ + requires_backends(self, ["torch", "cv2"]) + boxes = outputs.pred_boxes + logits = outputs.logits + order_logits = outputs.order_logits + masks = outputs.out_masks + + order_seqs = self._get_order_seqs(order_logits) + + box_centers, box_dims = torch.split(boxes, 2, dim=-1) + top_left_coords = box_centers - 0.5 * box_dims + bottom_right_coords = box_centers + 0.5 * box_dims + boxes = torch.cat([top_left_coords, bottom_right_coords], dim=-1) + + if target_sizes is not None: + if len(logits) != len(target_sizes): + raise ValueError( + "Make sure that you pass in as many target sizes as the batch dimension of the logits" + ) + if isinstance(target_sizes, list): + img_height, img_width = torch.as_tensor(target_sizes).unbind(1) + else: + img_height, img_width = target_sizes.unbind(1) + scale_factor = torch.stack([img_width, img_height, img_width, img_height], dim=1).to(boxes.device) + boxes = boxes * scale_factor[:, None, :] + + num_top_queries = logits.shape[1] + num_classes = logits.shape[2] + + scores = torch.nn.functional.sigmoid(logits) + scores, index = torch.topk(scores.flatten(1), num_top_queries, dim=-1) + labels = index % num_classes + index = index // num_classes + boxes = boxes.gather(dim=1, index=index.unsqueeze(-1).repeat(1, 1, boxes.shape[-1])) + masks = masks.gather( + dim=1, index=index.unsqueeze(-1).unsqueeze(-1).repeat(1, 1, masks.shape[-2], masks.shape[-1]) + ) + masks = (masks.sigmoid() > threshold).int() + order_seqs = order_seqs.gather(dim=1, index=index) + + results = [] + for score, label, box, order_seq, target_size, mask in zip( + scores, labels, boxes, order_seqs, target_sizes, masks + ): + order_seq = order_seq[score >= threshold] + order_seq, indices = torch.sort(order_seq) + polygon_points = self._extract_polygon_points_by_masks( + box[score >= threshold][indices].detach().cpu().numpy(), + mask[score >= threshold][indices].detach().cpu().numpy(), + [self.size["width"] / target_size[1], self.size["height"] / target_size[0]], + ) + results.append( + { + "scores": score[score >= threshold][indices], + "labels": label[score >= threshold][indices], + "boxes": box[score >= threshold][indices], + "polygon_points": polygon_points, + "order_seq": order_seq, + } + ) + + return results + + +__all__ = ["PPDocLayoutV3ImageProcessorFast"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pp_doclayout_v3/modeling_pp_doclayout_v3.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pp_doclayout_v3/modeling_pp_doclayout_v3.py new file mode 100644 index 0000000000000000000000000000000000000000..d4c275b93eed286956f0d8b9b434a34ace447356 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pp_doclayout_v3/modeling_pp_doclayout_v3.py @@ -0,0 +1,2085 @@ +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# This file was automatically generated from src/transformers/models/pp_doclayout_v3/modular_pp_doclayout_v3.py. +# Do NOT edit this file manually as any edits will be overwritten by the generation of +# the file from the modular. If any change should be done, please apply the change to the +# modular_pp_doclayout_v3.py file directly. One of our CI enforces this. +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# Copyright 2026 The PaddlePaddle Team and The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import math +import warnings +from collections.abc import Callable +from dataclasses import dataclass + +import numpy as np +import torch +import torch.nn.functional as F +from torch import Tensor, nn + +from ... import initialization as init +from ...activations import ACT2CLS, ACT2FN +from ...backbone_utils import load_backbone +from ...image_transforms import center_to_corners_format, corners_to_center_format +from ...integrations import use_kernel_forward_from_hub +from ...modeling_outputs import BaseModelOutput +from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel +from ...processing_utils import Unpack +from ...pytorch_utils import compile_compatible_method_lru_cache +from ...utils import ( + ModelOutput, + TransformersKwargs, + auto_docstring, + torch_compilable_check, + torch_int, +) +from ...utils.generic import can_return_tuple, merge_with_config_defaults +from ...utils.output_capturing import capture_outputs +from .configuration_pp_doclayout_v3 import PPDocLayoutV3Config + + +class PPDocLayoutV3GlobalPointer(nn.Module): + def __init__(self, config): + super().__init__() + self.head_size = config.global_pointer_head_size + self.dense = nn.Linear(config.d_model, self.head_size * 2) + self.dropout = nn.Dropout(config.gp_dropout_value) + + def forward(self, inputs): + batch_size, sequence_length, _ = inputs.shape + query_key_projection = self.dense(inputs).reshape(batch_size, sequence_length, 2, self.head_size) + query_key_projection = self.dropout(query_key_projection) + queries, keys = torch.unbind(query_key_projection, dim=2) + + logits = (queries @ keys.transpose(-2, -1)) / (self.head_size**0.5) + mask = torch.tril(torch.ones(sequence_length, sequence_length, device=logits.device)).bool() + logits = logits.masked_fill(mask.unsqueeze(0), -1e4) + + return logits + + +@use_kernel_forward_from_hub("MultiScaleDeformableAttention") +class MultiScaleDeformableAttention(nn.Module): + def forward( + self, + value: Tensor, + value_spatial_shapes: Tensor, + value_spatial_shapes_list: list[tuple], + level_start_index: Tensor, + sampling_locations: Tensor, + attention_weights: Tensor, + im2col_step: int, + ): + batch_size, _, num_heads, hidden_dim = value.shape + _, num_queries, num_heads, num_levels, num_points, _ = sampling_locations.shape + value_list = value.split([height * width for height, width in value_spatial_shapes_list], dim=1) + sampling_grids = 2 * sampling_locations - 1 + sampling_value_list = [] + for level_id, (height, width) in enumerate(value_spatial_shapes_list): + # batch_size, height*width, num_heads, hidden_dim + # -> batch_size, height*width, num_heads*hidden_dim + # -> batch_size, num_heads*hidden_dim, height*width + # -> batch_size*num_heads, hidden_dim, height, width + value_l_ = ( + value_list[level_id] + .flatten(2) + .transpose(1, 2) + .reshape(batch_size * num_heads, hidden_dim, height, width) + ) + # batch_size, num_queries, num_heads, num_points, 2 + # -> batch_size, num_heads, num_queries, num_points, 2 + # -> batch_size*num_heads, num_queries, num_points, 2 + sampling_grid_l_ = sampling_grids[:, :, :, level_id].transpose(1, 2).flatten(0, 1) + # batch_size*num_heads, hidden_dim, num_queries, num_points + sampling_value_l_ = nn.functional.grid_sample( + value_l_, + sampling_grid_l_, + mode="bilinear", + padding_mode="zeros", + align_corners=False, + ) + sampling_value_list.append(sampling_value_l_) + # (batch_size, num_queries, num_heads, num_levels, num_points) + # -> (batch_size, num_heads, num_queries, num_levels, num_points) + # -> (batch_size, num_heads, 1, num_queries, num_levels*num_points) + attention_weights = attention_weights.transpose(1, 2).reshape( + batch_size * num_heads, 1, num_queries, num_levels * num_points + ) + output = ( + (torch.stack(sampling_value_list, dim=-2).flatten(-2) * attention_weights) + .sum(-1) + .view(batch_size, num_heads * hidden_dim, num_queries) + ) + return output.transpose(1, 2).contiguous() + + +class PPDocLayoutV3MultiscaleDeformableAttention(nn.Module): + """ + Multiscale deformable attention as proposed in Deformable DETR. + """ + + def __init__(self, config: PPDocLayoutV3Config, num_heads: int, n_points: int): + super().__init__() + + self.attn = MultiScaleDeformableAttention() + + if config.d_model % num_heads != 0: + raise ValueError( + f"embed_dim (d_model) must be divisible by num_heads, but got {config.d_model} and {num_heads}" + ) + dim_per_head = config.d_model // num_heads + # check if dim_per_head is power of 2 + if not ((dim_per_head & (dim_per_head - 1) == 0) and dim_per_head != 0): + warnings.warn( + "You'd better set embed_dim (d_model) in PPDocLayoutV3MultiscaleDeformableAttention to make the" + " dimension of each attention head a power of 2 which is more efficient in the authors' CUDA" + " implementation." + ) + + self.im2col_step = 64 + + self.d_model = config.d_model + self.n_levels = config.num_feature_levels + self.n_heads = num_heads + self.n_points = n_points + + self.sampling_offsets = nn.Linear(config.d_model, num_heads * self.n_levels * n_points * 2) + self.attention_weights = nn.Linear(config.d_model, num_heads * self.n_levels * n_points) + self.value_proj = nn.Linear(config.d_model, config.d_model) + self.output_proj = nn.Linear(config.d_model, config.d_model) + + self.disable_custom_kernels = config.disable_custom_kernels + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.Tensor | None = None, + encoder_hidden_states=None, + encoder_attention_mask=None, + position_embeddings: torch.Tensor | None = None, + reference_points=None, + spatial_shapes=None, + spatial_shapes_list=None, + level_start_index=None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor, torch.Tensor]: + # add position embeddings to the hidden states before projecting to queries and keys + if position_embeddings is not None: + hidden_states = hidden_states + position_embeddings + + batch_size, num_queries, _ = hidden_states.shape + batch_size, sequence_length, _ = encoder_hidden_states.shape + total_elements = sum(height * width for height, width in spatial_shapes_list) + torch_compilable_check( + total_elements == sequence_length, + "Make sure to align the spatial shapes with the sequence length of the encoder hidden states", + ) + + value = self.value_proj(encoder_hidden_states) + if attention_mask is not None: + # we invert the attention_mask + value = value.masked_fill(~attention_mask[..., None], float(0)) + value = value.view(batch_size, sequence_length, self.n_heads, self.d_model // self.n_heads) + sampling_offsets = self.sampling_offsets(hidden_states).view( + batch_size, num_queries, self.n_heads, self.n_levels, self.n_points, 2 + ) + attention_weights = self.attention_weights(hidden_states).view( + batch_size, num_queries, self.n_heads, self.n_levels * self.n_points + ) + attention_weights = F.softmax(attention_weights, -1).view( + batch_size, num_queries, self.n_heads, self.n_levels, self.n_points + ) + # batch_size, num_queries, n_heads, n_levels, n_points, 2 + num_coordinates = reference_points.shape[-1] + if num_coordinates == 2: + offset_normalizer = torch.stack([spatial_shapes[..., 1], spatial_shapes[..., 0]], -1) + sampling_locations = ( + reference_points[:, :, None, :, None, :] + + sampling_offsets / offset_normalizer[None, None, None, :, None, :] + ) + elif num_coordinates == 4: + sampling_locations = ( + reference_points[:, :, None, :, None, :2] + + sampling_offsets / self.n_points * reference_points[:, :, None, :, None, 2:] * 0.5 + ) + else: + raise ValueError(f"Last dim of reference_points must be 2 or 4, but got {reference_points.shape[-1]}") + + output = self.attn( + value, + spatial_shapes, + spatial_shapes_list, + level_start_index, + sampling_locations, + attention_weights, + self.im2col_step, + ) + + output = self.output_proj(output) + + return output, attention_weights + + +@auto_docstring +class PPDocLayoutV3PreTrainedModel(PreTrainedModel): + config: PPDocLayoutV3Config + base_model_prefix = "pp_doclayout_v3" + main_input_name = "pixel_values" + input_modalities = ("image",) + _no_split_modules = [r"PPDocLayoutV3HybridEncoder", r"PPDocLayoutV3DecoderLayer"] + _supports_sdpa = True + _supports_flash_attn = True + _supports_attention_backend = True + _supports_flex_attn = True + + @torch.no_grad() + def _init_weights(self, module): + """Initialize the weights""" + if isinstance(module, PPDocLayoutV3MultiscaleDeformableAttention): + init.constant_(module.sampling_offsets.weight, 0.0) + default_dtype = torch.get_default_dtype() + thetas = torch.arange(module.n_heads, dtype=torch.int64).to(default_dtype) * ( + 2.0 * math.pi / module.n_heads + ) + grid_init = torch.stack([thetas.cos(), thetas.sin()], -1) + grid_init = ( + (grid_init / grid_init.abs().max(-1, keepdim=True)[0]) + .view(module.n_heads, 1, 1, 2) + .repeat(1, module.n_levels, module.n_points, 1) + ) + for i in range(module.n_points): + grid_init[:, :, i, :] *= i + 1 + + init.copy_(module.sampling_offsets.bias, grid_init.view(-1)) + init.constant_(module.attention_weights.weight, 0.0) + init.constant_(module.attention_weights.bias, 0.0) + init.xavier_uniform_(module.value_proj.weight) + init.constant_(module.value_proj.bias, 0.0) + init.xavier_uniform_(module.output_proj.weight) + init.constant_(module.output_proj.bias, 0.0) + + elif isinstance(module, PPDocLayoutV3Model): + prior_prob = self.config.initializer_bias_prior_prob or 1 / (self.config.num_labels + 1) + bias = float(-math.log((1 - prior_prob) / prior_prob)) + init.xavier_uniform_(module.enc_score_head.weight) + init.constant_(module.enc_score_head.bias, bias) + init.xavier_uniform_(module.decoder.class_embed.weight) + init.constant_(module.decoder.class_embed.bias, bias) + + elif isinstance(module, (nn.Linear, nn.Conv2d, nn.BatchNorm2d)): + init.normal_(module.weight, mean=0.0, std=self.config.initializer_range) + if module.bias is not None: + init.zeros_(module.bias) + if getattr(module, "running_mean", None) is not None: + init.zeros_(module.running_mean) + init.ones_(module.running_var) + init.zeros_(module.num_batches_tracked) + + elif isinstance(module, nn.LayerNorm): + init.ones_(module.weight) + init.zeros_(module.bias) + + if isinstance(module, nn.Embedding): + init.normal_(module.weight, mean=0.0, std=self.config.initializer_range) + if module.padding_idx is not None: + init.zeros_(module.weight.data[module.padding_idx]) + + +@dataclass +class PPDocLayoutV3DecoderOutput(ModelOutput): + r""" + intermediate_hidden_states (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, hidden_size)`): + Stacked intermediate hidden states (output of each layer of the decoder). + intermediate_logits (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, sequence_length, config.num_labels)`): + Stacked intermediate logits (logits of each layer of the decoder). + intermediate_reference_points (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, sequence_length, hidden_size)`): + Stacked intermediate reference points (reference points of each layer of the decoder). + intermediate_predicted_corners (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, 4)`): + Stacked intermediate predicted corners (predicted corners of each layer of the decoder). + initial_reference_points (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, 4)`): + Stacked initial reference points (initial reference points of each layer of the decoder). + cross_attentions (`tuple(torch.FloatTensor)`, *optional*, returned when `output_attentions=True` and `config.add_cross_attention=True` is passed or when `config.output_attentions=True`): + Tuple of `torch.FloatTensor` (one for each layer) of shape `(batch_size, num_heads, sequence_length, + sequence_length)`. Attentions weights of the decoder's cross-attention layer, after the attention softmax, + used to compute the weighted average in the cross-attention heads. + decoder_out_order_logits (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, config.num_queries, config.num_queries)`): + Stacked order logits (order logits of each layer of the decoder). + decoder_out_masks (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, config.num_queries, 200, 200)`): + Stacked masks (masks of each layer of the decoder). + """ + + last_hidden_state: torch.FloatTensor | None = None + intermediate_hidden_states: torch.FloatTensor | None = None + intermediate_logits: torch.FloatTensor | None = None + intermediate_reference_points: torch.FloatTensor | None = None + intermediate_predicted_corners: torch.FloatTensor | None = None + initial_reference_points: torch.FloatTensor | None = None + hidden_states: tuple[torch.FloatTensor] | None = None + attentions: tuple[torch.FloatTensor] | None = None + cross_attentions: tuple[torch.FloatTensor] | None = None + + decoder_out_order_logits: torch.FloatTensor | None = None + decoder_out_masks: torch.FloatTensor | None = None + + +@dataclass +@auto_docstring( + custom_intro=""" + Base class for outputs of the PP-DocLayoutV3 model. + """ +) +class PPDocLayoutV3ModelOutput(ModelOutput): + r""" + last_hidden_state (`torch.FloatTensor` of shape `(batch_size, num_queries, hidden_size)`): + Sequence of hidden-states at the output of the last layer of the decoder of the model. + intermediate_hidden_states (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, hidden_size)`): + Stacked intermediate hidden states (output of each layer of the decoder). + intermediate_logits (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, sequence_length, config.num_labels)`): + Stacked intermediate logits (logits of each layer of the decoder). + intermediate_reference_points (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, 4)`): + Stacked intermediate reference points (reference points of each layer of the decoder). + intermediate_predicted_corners (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, 4)`): + Stacked intermediate predicted corners (predicted corners of each layer of the decoder). + initial_reference_points (`torch.FloatTensor` of shape `(batch_size, num_queries, 4)`): + Initial reference points used for the first decoder layer. + init_reference_points (`torch.FloatTensor` of shape `(batch_size, num_queries, 4)`): + Initial reference points sent through the Transformer decoder. + enc_topk_logits (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.num_labels)`): + Predicted bounding boxes scores where the top `config.two_stage_num_proposals` scoring bounding boxes are + picked as region proposals in the encoder stage. Output of bounding box binary classification (i.e. + foreground and background). + enc_topk_bboxes (`torch.FloatTensor` of shape `(batch_size, sequence_length, 4)`): + Logits of predicted bounding boxes coordinates in the encoder stage. + enc_outputs_class (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.num_labels)`, *optional*, returned when `config.with_box_refine=True` and `config.two_stage=True`): + Predicted bounding boxes scores where the top `config.two_stage_num_proposals` scoring bounding boxes are + picked as region proposals in the first stage. Output of bounding box binary classification (i.e. + foreground and background). + enc_outputs_coord_logits (`torch.FloatTensor` of shape `(batch_size, sequence_length, 4)`, *optional*, returned when `config.with_box_refine=True` and `config.two_stage=True`): + Logits of predicted bounding boxes coordinates in the first stage. + denoising_meta_values (`dict`): + Extra dictionary for the denoising related values. + out_order_logits (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, config.num_queries, config.num_queries)`): + Stacked order logits (order logits of each layer of the decoder). + out_masks (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, config.num_queries, 200, 200)`): + Stacked masks (masks of each layer of the decoder). + """ + + last_hidden_state: torch.FloatTensor | None = None + intermediate_hidden_states: torch.FloatTensor | None = None + intermediate_logits: torch.FloatTensor | None = None + intermediate_reference_points: torch.FloatTensor | None = None + intermediate_predicted_corners: torch.FloatTensor | None = None + initial_reference_points: torch.FloatTensor | None = None + decoder_hidden_states: tuple[torch.FloatTensor] | None = None + decoder_attentions: tuple[torch.FloatTensor] | None = None + cross_attentions: tuple[torch.FloatTensor] | None = None + encoder_last_hidden_state: torch.FloatTensor | None = None + encoder_hidden_states: tuple[torch.FloatTensor] | None = None + encoder_attentions: tuple[torch.FloatTensor] | None = None + init_reference_points: torch.FloatTensor | None = None + enc_topk_logits: torch.FloatTensor | None = None + enc_topk_bboxes: torch.FloatTensor | None = None + enc_outputs_class: torch.FloatTensor | None = None + enc_outputs_coord_logits: torch.FloatTensor | None = None + denoising_meta_values: dict | None = None + + out_order_logits: torch.FloatTensor | None = None + out_masks: torch.FloatTensor | None = None + + +class PPDocLayoutV3MLPPredictionHead(nn.Module): + """ + Very simple multi-layer perceptron (MLP, also called FFN), used to predict the normalized center coordinates, + height and width of a bounding box w.r.t. an image. + + """ + + def __init__(self, input_dim, hidden_dim, output_dim, num_layers): + super().__init__() + self.num_layers = num_layers + h = [hidden_dim] * (num_layers - 1) + self.layers = nn.ModuleList(nn.Linear(n, k) for n, k in zip([input_dim] + h, h + [output_dim])) + + def forward(self, x): + for i, layer in enumerate(self.layers): + x = nn.functional.relu(layer(x)) if i < self.num_layers - 1 else layer(x) + return x + + +class PPDocLayoutV3ConvLayer(nn.Module): + def __init__( + self, in_channels: int, out_channels: int, kernel_size: int = 3, stride: int = 1, activation: str = "relu" + ): + super().__init__() + self.convolution = nn.Conv2d( + in_channels, out_channels, kernel_size=kernel_size, stride=stride, padding=kernel_size // 2, bias=False + ) + self.normalization = nn.BatchNorm2d(out_channels) + self.activation = ACT2FN[activation] if activation is not None else nn.Identity() + + def forward(self, input: Tensor) -> Tensor: + hidden_state = self.convolution(input) + hidden_state = self.normalization(hidden_state) + hidden_state = self.activation(hidden_state) + return hidden_state + + +class PPDocLayoutV3ScaleHead(nn.Module): + def __init__(self, in_channels, feature_channels, fpn_stride, base_stride, align_corners=False): + super().__init__() + head_length = max(1, int(np.log2(fpn_stride) - np.log2(base_stride))) + self.layers = nn.ModuleList() + for k in range(head_length): + in_c = in_channels if k == 0 else feature_channels + self.layers.append(PPDocLayoutV3ConvLayer(in_c, feature_channels, 3, 1, "silu")) + if fpn_stride != base_stride: + self.layers.append(nn.Upsample(scale_factor=2, mode="bilinear", align_corners=align_corners)) + + def forward(self, x): + for layer in self.layers: + x = layer(x) + return x + + +class PPDocLayoutV3MaskFeatFPN(nn.Module): + def __init__( + self, + in_channels=[256, 256, 256], + fpn_strides=[32, 16, 8], + feature_channels=256, + dropout_ratio=0.0, + out_channels=256, + align_corners=False, + ): + super().__init__() + + reorder_index = np.argsort(fpn_strides, axis=0).tolist() + in_channels = [in_channels[i] for i in reorder_index] + fpn_strides = [fpn_strides[i] for i in reorder_index] + + self.reorder_index = reorder_index + self.fpn_strides = fpn_strides + self.dropout_ratio = dropout_ratio + self.align_corners = align_corners + if self.dropout_ratio > 0: + self.dropout = nn.Dropout2d(dropout_ratio) + + self.scale_heads = nn.ModuleList() + for i in range(len(fpn_strides)): + self.scale_heads.append( + PPDocLayoutV3ScaleHead( + in_channels=in_channels[i], + feature_channels=feature_channels, + fpn_stride=fpn_strides[i], + base_stride=fpn_strides[0], + align_corners=align_corners, + ) + ) + self.output_conv = PPDocLayoutV3ConvLayer(feature_channels, out_channels, 3, 1, "silu") + + def forward(self, inputs): + x = [inputs[i] for i in self.reorder_index] + + output = self.scale_heads[0](x[0]) + for i in range(1, len(self.fpn_strides)): + output = output + F.interpolate( + self.scale_heads[i](x[i]), size=output.shape[2:], mode="bilinear", align_corners=self.align_corners + ) + + if self.dropout_ratio > 0: + output = self.dropout(output) + output = self.output_conv(output) + return output + + +class PPDocLayoutV3EncoderMaskOutput(nn.Module): + def __init__(self, in_channels, num_prototypes): + super().__init__() + self.base_conv = PPDocLayoutV3ConvLayer(in_channels, in_channels, 3, 1, "silu") + self.conv = nn.Conv2d(in_channels, num_prototypes, kernel_size=1) + + def forward(self, x): + x = self.base_conv(x) + x = self.conv(x) + return x + + +class PPDocLayoutV3MLP(nn.Module): + def __init__( + self, config: PPDocLayoutV3Config, hidden_size: int, intermediate_size: int, activation_function: str + ): + super().__init__() + self.fc1 = nn.Linear(hidden_size, intermediate_size) + self.fc2 = nn.Linear(intermediate_size, hidden_size) + self.activation_fn = ACT2FN[activation_function] + self.activation_dropout = config.activation_dropout + self.dropout = config.dropout + + def forward(self, hidden_states: torch.Tensor) -> torch.Tensor: + hidden_states = self.activation_fn(self.fc1(hidden_states)) + hidden_states = nn.functional.dropout(hidden_states, p=self.activation_dropout, training=self.training) + hidden_states = self.fc2(hidden_states) + hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training) + return hidden_states + + +def eager_attention_forward( + module: nn.Module, + query: torch.Tensor, + key: torch.Tensor, + value: torch.Tensor, + attention_mask: torch.Tensor | None, + scaling: float | None = None, + dropout: float = 0.0, + **kwargs: Unpack[TransformersKwargs], +): + if scaling is None: + scaling = query.size(-1) ** -0.5 + + # Take the dot product between "query" and "key" to get the raw attention scores. + attn_weights = torch.matmul(query, key.transpose(2, 3)) * scaling + + if attention_mask is not None: + attn_weights = attn_weights + attention_mask + + attn_weights = nn.functional.softmax(attn_weights, dim=-1) + attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training) + + attn_output = torch.matmul(attn_weights, value) + attn_output = attn_output.transpose(1, 2).contiguous() + + return attn_output, attn_weights + + +class PPDocLayoutV3SelfAttention(nn.Module): + """ + Multi-headed self-attention from 'Attention Is All You Need' paper. + + In PP_DOCLAYOUT_V3, position embeddings are added to both queries and keys (but not values) in self-attention. + """ + + def __init__( + self, + config: PPDocLayoutV3Config, + hidden_size: int, + num_attention_heads: int, + dropout: float = 0.0, + bias: bool = True, + ): + super().__init__() + self.config = config + self.head_dim = hidden_size // num_attention_heads + self.scaling = self.head_dim**-0.5 + self.attention_dropout = dropout + self.is_causal = False + + self.k_proj = nn.Linear(hidden_size, hidden_size, bias=bias) + self.v_proj = nn.Linear(hidden_size, hidden_size, bias=bias) + self.q_proj = nn.Linear(hidden_size, hidden_size, bias=bias) + self.o_proj = nn.Linear(hidden_size, hidden_size, bias=bias) + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.Tensor | None = None, + position_embeddings: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor, torch.Tensor]: + """ + Position embeddings are added to both queries and keys (but not values). + """ + input_shape = hidden_states.shape[:-1] + hidden_shape = (*input_shape, -1, self.head_dim) + + query_key_input = hidden_states + position_embeddings if position_embeddings is not None else hidden_states + + query_states = self.q_proj(query_key_input).view(hidden_shape).transpose(1, 2) + key_states = self.k_proj(query_key_input).view(hidden_shape).transpose(1, 2) + value_states = self.v_proj(hidden_states).view(hidden_shape).transpose(1, 2) + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, eager_attention_forward + ) + + attn_output, attn_weights = attention_interface( + self, + query_states, + key_states, + value_states, + attention_mask, + dropout=0.0 if not self.training else self.attention_dropout, + scaling=self.scaling, + **kwargs, + ) + + attn_output = attn_output.reshape(*input_shape, -1).contiguous() + attn_output = self.o_proj(attn_output) + return attn_output, attn_weights + + +class PPDocLayoutV3ConvNormLayer(nn.Module): + def __init__(self, config, in_channels, out_channels, kernel_size, stride, padding=None, activation=None): + super().__init__() + self.conv = nn.Conv2d( + in_channels, + out_channels, + kernel_size, + stride, + padding=(kernel_size - 1) // 2 if padding is None else padding, + bias=False, + ) + self.norm = nn.BatchNorm2d(out_channels, config.batch_norm_eps) + self.activation = nn.Identity() if activation is None else ACT2CLS[activation]() + + def forward(self, hidden_state): + hidden_state = self.conv(hidden_state) + hidden_state = self.norm(hidden_state) + hidden_state = self.activation(hidden_state) + return hidden_state + + +class PPDocLayoutV3EncoderLayer(nn.Module): + def __init__(self, config: PPDocLayoutV3Config): + super().__init__() + self.normalize_before = config.normalize_before + self.hidden_size = config.encoder_hidden_dim + + # self-attention + self.self_attn = PPDocLayoutV3SelfAttention( + config=config, + hidden_size=self.hidden_size, + num_attention_heads=config.num_attention_heads, + dropout=config.dropout, + ) + self.self_attn_layer_norm = nn.LayerNorm(self.hidden_size, eps=config.layer_norm_eps) + self.dropout = config.dropout + self.mlp = PPDocLayoutV3MLP( + config, self.hidden_size, config.encoder_ffn_dim, config.encoder_activation_function + ) + self.final_layer_norm = nn.LayerNorm(self.hidden_size, eps=config.layer_norm_eps) + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.Tensor, + spatial_position_embeddings: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> torch.Tensor: + """ + Args: + hidden_states (`torch.FloatTensor`): input to the layer of shape `(batch, seq_len, hidden_size)` + attention_mask (`torch.FloatTensor`): attention mask of size + `(batch, 1, target_len, source_len)` where padding elements are indicated by very large negative + values. + spatial_position_embeddings (`torch.FloatTensor`, *optional*): + Spatial position embeddings (2D positional encodings of image locations), to be added to both + the queries and keys in self-attention (but not to values). + """ + residual = hidden_states + if self.normalize_before: + hidden_states = self.self_attn_layer_norm(hidden_states) + + hidden_states, _ = self.self_attn( + hidden_states=hidden_states, + attention_mask=attention_mask, + position_embeddings=spatial_position_embeddings, + **kwargs, + ) + + hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training) + hidden_states = residual + hidden_states + if not self.normalize_before: + hidden_states = self.self_attn_layer_norm(hidden_states) + + if self.normalize_before: + hidden_states = self.final_layer_norm(hidden_states) + residual = hidden_states + + hidden_states = self.mlp(hidden_states) + + hidden_states = residual + hidden_states + if not self.normalize_before: + hidden_states = self.final_layer_norm(hidden_states) + + if self.training: + if not torch.isfinite(hidden_states).all(): + clamp_value = torch.finfo(hidden_states.dtype).max - 1000 + hidden_states = torch.clamp(hidden_states, min=-clamp_value, max=clamp_value) + + return hidden_states + + +class PPDocLayoutV3RepVggBlock(nn.Module): + """ + RepVGG architecture block introduced by the work "RepVGG: Making VGG-style ConvNets Great Again". + """ + + def __init__(self, config: PPDocLayoutV3Config): + super().__init__() + + activation = config.activation_function + hidden_channels = int(config.encoder_hidden_dim * config.hidden_expansion) + self.conv1 = PPDocLayoutV3ConvNormLayer(config, hidden_channels, hidden_channels, 3, 1, padding=1) + self.conv2 = PPDocLayoutV3ConvNormLayer(config, hidden_channels, hidden_channels, 1, 1, padding=0) + self.activation = nn.Identity() if activation is None else ACT2CLS[activation]() + + def forward(self, x): + y = self.conv1(x) + self.conv2(x) + return self.activation(y) + + +class PPDocLayoutV3CSPRepLayer(nn.Module): + """ + Cross Stage Partial (CSP) network layer with RepVGG blocks. + """ + + def __init__(self, config: PPDocLayoutV3Config): + super().__init__() + + in_channels = config.encoder_hidden_dim * 2 + out_channels = config.encoder_hidden_dim + num_blocks = 3 + activation = config.activation_function + + hidden_channels = int(out_channels * config.hidden_expansion) + self.conv1 = PPDocLayoutV3ConvNormLayer(config, in_channels, hidden_channels, 1, 1, activation=activation) + self.conv2 = PPDocLayoutV3ConvNormLayer(config, in_channels, hidden_channels, 1, 1, activation=activation) + self.bottlenecks = nn.Sequential(*[PPDocLayoutV3RepVggBlock(config) for _ in range(num_blocks)]) + if hidden_channels != out_channels: + self.conv3 = PPDocLayoutV3ConvNormLayer(config, hidden_channels, out_channels, 1, 1, activation=activation) + else: + self.conv3 = nn.Identity() + + def forward(self, hidden_state): + hidden_state_1 = self.conv1(hidden_state) + hidden_state_1 = self.bottlenecks(hidden_state_1) + hidden_state_2 = self.conv2(hidden_state) + return self.conv3(hidden_state_1 + hidden_state_2) + + +class PPDocLayoutV3SinePositionEmbedding(nn.Module): + """ + 2D sinusoidal position embedding used in RT-DETR hybrid encoder. + """ + + def __init__(self, embed_dim: int = 256, temperature: int = 10000): + super().__init__() + self.embed_dim = embed_dim + self.temperature = temperature + + @compile_compatible_method_lru_cache(maxsize=32) + def forward( + self, + width: int, + height: int, + device: torch.device | str, + dtype: torch.dtype, + ) -> torch.Tensor: + """ + Generate 2D sinusoidal position embeddings. + + Returns: + Position embeddings of shape (1, height*width, embed_dim) + """ + grid_w = torch.arange(torch_int(width), device=device).to(dtype) + grid_h = torch.arange(torch_int(height), device=device).to(dtype) + grid_w, grid_h = torch.meshgrid(grid_w, grid_h, indexing="xy") + if self.embed_dim % 4 != 0: + raise ValueError("Embed dimension must be divisible by 4 for 2D sin-cos position embedding") + pos_dim = self.embed_dim // 4 + omega = torch.arange(pos_dim, device=device).to(dtype) / pos_dim + omega = 1.0 / (self.temperature**omega) + + out_w = grid_w.flatten()[..., None] @ omega[None] + out_h = grid_h.flatten()[..., None] @ omega[None] + + return torch.concat([out_h.sin(), out_h.cos(), out_w.sin(), out_w.cos()], dim=1)[None, :, :] + + +class PPDocLayoutV3AIFILayer(nn.Module): + """ + AIFI (Attention-based Intra-scale Feature Interaction) layer used in RT-DETR hybrid encoder. + """ + + def __init__(self, config: PPDocLayoutV3Config): + super().__init__() + self.config = config + self.encoder_hidden_dim = config.encoder_hidden_dim + self.eval_size = config.eval_size + + self.position_embedding = PPDocLayoutV3SinePositionEmbedding( + embed_dim=self.encoder_hidden_dim, + temperature=config.positional_encoding_temperature, + ) + self.layers = nn.ModuleList([PPDocLayoutV3EncoderLayer(config) for _ in range(config.encoder_layers)]) + + def forward( + self, + hidden_states: torch.Tensor, + **kwargs: Unpack[TransformersKwargs], + ) -> torch.Tensor: + """ + Args: + hidden_states (`torch.FloatTensor` of shape `(batch_size, channels, height, width)`): + Feature map to process. + """ + batch_size = hidden_states.shape[0] + height, width = hidden_states.shape[2:] + + hidden_states = hidden_states.flatten(2).permute(0, 2, 1) + + if self.training or self.eval_size is None: + pos_embed = self.position_embedding( + width=width, + height=height, + device=hidden_states.device, + dtype=hidden_states.dtype, + ) + else: + pos_embed = None + + for layer in self.layers: + hidden_states = layer( + hidden_states, + attention_mask=None, + spatial_position_embeddings=pos_embed, + **kwargs, + ) + + hidden_states = ( + hidden_states.permute(0, 2, 1).reshape(batch_size, self.encoder_hidden_dim, height, width).contiguous() + ) + + return hidden_states + + +class PPDocLayoutV3HybridEncoder(PPDocLayoutV3PreTrainedModel): + """ + Main difference to `RTDetrHybridEncoder`: + 1. Mask Feature Head: Added `PPDocLayoutV3MaskFeatFPN` module (`self.mask_feature_head`) for document - specific mask feature generation. + 2. Extra Conv Layers: Introduced `self.encoder_mask_lateral` and `self.encoder_mask_output` for mask feature processing and output. + """ + + _can_record_outputs = { + "hidden_states": PPDocLayoutV3AIFILayer, + "attentions": PPDocLayoutV3SelfAttention, + } + + def __init__(self, config: PPDocLayoutV3Config): + super().__init__(config) + self.config = config + self.in_channels = config.encoder_in_channels + self.feat_strides = config.feat_strides + self.encoder_hidden_dim = config.encoder_hidden_dim + self.encode_proj_layers = config.encode_proj_layers + self.positional_encoding_temperature = config.positional_encoding_temperature + self.eval_size = config.eval_size + self.out_channels = [self.encoder_hidden_dim for _ in self.in_channels] + self.out_strides = self.feat_strides + self.num_fpn_stages = len(self.in_channels) - 1 + self.num_pan_stages = len(self.in_channels) - 1 + + # AIFI (Attention-based Intra-scale Feature Interaction) layers + self.aifi = nn.ModuleList([PPDocLayoutV3AIFILayer(config) for _ in range(len(self.encode_proj_layers))]) + + # top-down FPN + self.lateral_convs = nn.ModuleList() + self.fpn_blocks = nn.ModuleList() + for _ in range(self.num_fpn_stages): + lateral_conv = PPDocLayoutV3ConvNormLayer( + config, + in_channels=self.encoder_hidden_dim, + out_channels=self.encoder_hidden_dim, + kernel_size=1, + stride=1, + activation=config.activation_function, + ) + fpn_block = PPDocLayoutV3CSPRepLayer(config) + self.lateral_convs.append(lateral_conv) + self.fpn_blocks.append(fpn_block) + + # bottom-up PAN + self.downsample_convs = nn.ModuleList() + self.pan_blocks = nn.ModuleList() + for _ in range(self.num_pan_stages): + downsample_conv = PPDocLayoutV3ConvNormLayer( + config, + in_channels=self.encoder_hidden_dim, + out_channels=self.encoder_hidden_dim, + kernel_size=3, + stride=2, + activation=config.activation_function, + ) + pan_block = PPDocLayoutV3CSPRepLayer(config) + self.downsample_convs.append(downsample_conv) + self.pan_blocks.append(pan_block) + + feat_strides = config.feat_strides + mask_feature_channels = config.mask_feature_channels + self.mask_feature_head = PPDocLayoutV3MaskFeatFPN( + [self.encoder_hidden_dim] * len(feat_strides), + feat_strides, + feature_channels=mask_feature_channels[0], + out_channels=mask_feature_channels[1], + ) + self.encoder_mask_lateral = PPDocLayoutV3ConvLayer(config.x4_feat_dim, mask_feature_channels[1], 3, 1, "silu") + self.encoder_mask_output = PPDocLayoutV3EncoderMaskOutput( + in_channels=mask_feature_channels[1], num_prototypes=config.num_prototypes + ) + + self.post_init() + + @merge_with_config_defaults + @capture_outputs(tie_last_hidden_states=False) + def forward( + self, + inputs_embeds=None, + x4_feat=None, + **kwargs: Unpack[TransformersKwargs], + ) -> BaseModelOutput: + r""" + Args: + inputs_embeds (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`): + Flattened feature map (output of the backbone + projection layer) that is passed to the encoder. + """ + feature_maps = inputs_embeds + + # AIFI: Apply transformer encoder to specified feature levels + if self.config.encoder_layers > 0: + for i, enc_ind in enumerate(self.encode_proj_layers): + feature_maps[enc_ind] = self.aifi[i](feature_maps[enc_ind], **kwargs) + + # top-down FPN + fpn_feature_maps = [feature_maps[-1]] + for idx, (lateral_conv, fpn_block) in enumerate(zip(self.lateral_convs, self.fpn_blocks)): + backbone_feature_map = feature_maps[self.num_fpn_stages - idx - 1] + top_fpn_feature_map = fpn_feature_maps[-1] + # apply lateral block + top_fpn_feature_map = lateral_conv(top_fpn_feature_map) + fpn_feature_maps[-1] = top_fpn_feature_map + # apply fpn block + top_fpn_feature_map = F.interpolate(top_fpn_feature_map, scale_factor=2.0, mode="nearest") + fused_feature_map = torch.concat([top_fpn_feature_map, backbone_feature_map], dim=1) + new_fpn_feature_map = fpn_block(fused_feature_map) + fpn_feature_maps.append(new_fpn_feature_map) + + fpn_feature_maps.reverse() + + # bottom-up PAN + pan_feature_maps = [fpn_feature_maps[0]] + for idx, (downsample_conv, pan_block) in enumerate(zip(self.downsample_convs, self.pan_blocks)): + top_pan_feature_map = pan_feature_maps[-1] + fpn_feature_map = fpn_feature_maps[idx + 1] + downsampled_feature_map = downsample_conv(top_pan_feature_map) + fused_feature_map = torch.concat([downsampled_feature_map, fpn_feature_map], dim=1) + new_pan_feature_map = pan_block(fused_feature_map) + pan_feature_maps.append(new_pan_feature_map) + + mask_feat = self.mask_feature_head(pan_feature_maps) + mask_feat = F.interpolate(mask_feat, scale_factor=2, mode="bilinear", align_corners=False) + mask_feat += self.encoder_mask_lateral(x4_feat[0]) + mask_feat = self.encoder_mask_output(mask_feat) + + return PPDocLayoutV3HybridEncoderOutput( + last_hidden_state=pan_feature_maps, + mask_feat=mask_feat, + ) + + +class PPDocLayoutV3DecoderLayer(nn.Module): + def __init__(self, config: PPDocLayoutV3Config): + super().__init__() + self.hidden_size = config.d_model + + # self-attention + self.self_attn = PPDocLayoutV3SelfAttention( + config=config, + hidden_size=self.hidden_size, + num_attention_heads=config.decoder_attention_heads, + dropout=config.attention_dropout, + ) + self.dropout = config.dropout + + self.self_attn_layer_norm = nn.LayerNorm(self.hidden_size, eps=config.layer_norm_eps) + # cross-attention + self.encoder_attn = PPDocLayoutV3MultiscaleDeformableAttention( + config, + num_heads=config.decoder_attention_heads, + n_points=config.decoder_n_points, + ) + self.encoder_attn_layer_norm = nn.LayerNorm(self.hidden_size, eps=config.layer_norm_eps) + # feedforward neural networks + self.mlp = PPDocLayoutV3MLP( + config, self.hidden_size, config.decoder_ffn_dim, config.decoder_activation_function + ) + self.final_layer_norm = nn.LayerNorm(self.hidden_size, eps=config.layer_norm_eps) + + def forward( + self, + hidden_states: torch.Tensor, + object_queries_position_embeddings: torch.Tensor | None = None, + reference_points=None, + spatial_shapes=None, + spatial_shapes_list=None, + level_start_index=None, + encoder_hidden_states: torch.Tensor | None = None, + encoder_attention_mask: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> torch.Tensor: + """ + Args: + hidden_states (`torch.FloatTensor`): + Input to the layer of shape `(batch, seq_len, hidden_size)`. + object_queries_position_embeddings (`torch.FloatTensor`, *optional*): + Position embeddings for the object query slots. These are added to both queries and keys + in the self-attention layer (not values). + reference_points (`torch.FloatTensor`, *optional*): + Reference points. + spatial_shapes (`torch.LongTensor`, *optional*): + Spatial shapes. + level_start_index (`torch.LongTensor`, *optional*): + Level start index. + encoder_hidden_states (`torch.FloatTensor`): + cross attention input to the layer of shape `(batch, seq_len, hidden_size)` + encoder_attention_mask (`torch.FloatTensor`): encoder attention mask of size + `(batch, 1, target_len, source_len)` where padding elements are indicated by very large negative + values. + """ + residual = hidden_states + + # Self Attention + hidden_states, _ = self.self_attn( + hidden_states=hidden_states, + attention_mask=encoder_attention_mask, + position_embeddings=object_queries_position_embeddings, + **kwargs, + ) + + hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training) + hidden_states = residual + hidden_states + hidden_states = self.self_attn_layer_norm(hidden_states) + + residual = hidden_states + + # Cross-Attention + hidden_states, _ = self.encoder_attn( + hidden_states=hidden_states, + encoder_hidden_states=encoder_hidden_states, + position_embeddings=object_queries_position_embeddings, + reference_points=reference_points, + spatial_shapes=spatial_shapes, + spatial_shapes_list=spatial_shapes_list, + level_start_index=level_start_index, + **kwargs, + ) + + hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training) + hidden_states = residual + hidden_states + + hidden_states = self.encoder_attn_layer_norm(hidden_states) + + # Fully Connected + residual = hidden_states + hidden_states = self.mlp(hidden_states) + hidden_states = residual + hidden_states + hidden_states = self.final_layer_norm(hidden_states) + + return hidden_states + + +def inverse_sigmoid(x, eps=1e-5): + x = x.clamp(min=0, max=1) + x1 = x.clamp(min=eps) + x2 = (1 - x).clamp(min=eps) + return torch.log(x1 / x2) + + +class PPDocLayoutV3Decoder(PPDocLayoutV3PreTrainedModel): + """ + Main difference to `RTDetrDecoder`: + A new mask generation process is introduced at each decoder layer. + """ + + _can_record_outputs = { + "hidden_states": PPDocLayoutV3DecoderLayer, + "attentions": PPDocLayoutV3SelfAttention, + "cross_attentions": PPDocLayoutV3MultiscaleDeformableAttention, + } + + def __init__(self, config: PPDocLayoutV3Config): + super().__init__(config) + + self.dropout = config.dropout + self.layers = nn.ModuleList([PPDocLayoutV3DecoderLayer(config) for _ in range(config.decoder_layers)]) + self.query_pos_head = PPDocLayoutV3MLPPredictionHead(4, 2 * config.d_model, config.d_model, num_layers=2) + + # hack implementation for iterative bounding box refinement and two-stage Deformable DETR + self.bbox_embed = None + self.class_embed = None + + self.num_queries = config.num_queries + + # Initialize weights and apply final processing + self.post_init() + + @merge_with_config_defaults + @capture_outputs + def forward( + self, + inputs_embeds=None, + encoder_hidden_states=None, + encoder_attention_mask=None, + reference_points=None, + spatial_shapes=None, + spatial_shapes_list=None, + level_start_index=None, + order_head=None, + global_pointer=None, + mask_query_head=None, + norm=None, + mask_feat=None, + **kwargs: Unpack[TransformersKwargs], + ): + r""" + Args: + inputs_embeds (`torch.FloatTensor` of shape `(batch_size, num_queries, hidden_size)`): + The query embeddings that are passed into the decoder. + encoder_hidden_states (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*): + Sequence of hidden-states at the output of the last layer of the encoder. Used in the cross-attention + of the decoder. + encoder_attention_mask (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Mask to avoid performing cross-attention on padding pixel_values of the encoder. Mask values selected + in `[0, 1]`: + - 1 for pixels that are real (i.e. **not masked**), + - 0 for pixels that are padding (i.e. **masked**). + reference_points (`torch.FloatTensor` of shape `(batch_size, num_queries, 4)` is `as_two_stage` else `(batch_size, num_queries, 2)` or , *optional*): + Reference point in range `[0, 1]`, top-left (0,0), bottom-right (1, 1), including padding area. + spatial_shapes (`torch.FloatTensor` of shape `(num_feature_levels, 2)`): + Spatial shapes of the feature maps. + level_start_index (`torch.LongTensor` of shape `(num_feature_levels)`, *optional*): + Indexes for the start of each feature level. In range `[0, sequence_length]`. + """ + if inputs_embeds is not None: + hidden_states = inputs_embeds + + # decoder layers + intermediate = () + intermediate_reference_points = () + intermediate_logits = () + decoder_out_order_logits = () + decoder_out_masks = () + + reference_points = F.sigmoid(reference_points) + + # https://github.com/lyuwenyu/RT-DETR/blob/94f5e16708329d2f2716426868ec89aa774af016/rtdetr_pytorch/src/zoo/rtdetr/rtdetr_decoder.py#L252 + for idx, decoder_layer in enumerate(self.layers): + reference_points_input = reference_points.unsqueeze(2) + object_queries_position_embeddings = self.query_pos_head(reference_points) + + hidden_states = decoder_layer( + hidden_states, + object_queries_position_embeddings=object_queries_position_embeddings, + encoder_hidden_states=encoder_hidden_states, + reference_points=reference_points_input, + spatial_shapes=spatial_shapes, + spatial_shapes_list=spatial_shapes_list, + level_start_index=level_start_index, + encoder_attention_mask=encoder_attention_mask, + **kwargs, + ) + + # hack implementation for iterative bounding box refinement + if self.bbox_embed is not None: + predicted_corners = self.bbox_embed(hidden_states) + new_reference_points = F.sigmoid(predicted_corners + inverse_sigmoid(reference_points)) + reference_points = new_reference_points.detach() + + intermediate += (hidden_states,) + intermediate_reference_points += ( + (new_reference_points,) if self.bbox_embed is not None else (reference_points,) + ) + + # get_pred_class_order_and_mask + out_query = norm(hidden_states) + mask_query_embed = mask_query_head(out_query) + batch_size, mask_dim, _ = mask_query_embed.shape + _, _, mask_h, mask_w = mask_feat.shape + out_mask = torch.bmm(mask_query_embed, mask_feat.flatten(start_dim=2)).reshape( + batch_size, mask_dim, mask_h, mask_w + ) + decoder_out_masks += (out_mask,) + + if self.class_embed is not None: + logits = self.class_embed(out_query) + intermediate_logits += (logits,) + + if order_head is not None and global_pointer is not None: + valid_query = out_query[:, -self.num_queries :] if self.num_queries is not None else out_query + order_logits = global_pointer(order_head[idx](valid_query)) + decoder_out_order_logits += (order_logits,) + + # Keep batch_size as first dimension + intermediate = torch.stack(intermediate, dim=1) + intermediate_reference_points = torch.stack(intermediate_reference_points, dim=1) + if self.class_embed is not None: + intermediate_logits = torch.stack(intermediate_logits, dim=1) + if order_head is not None and global_pointer is not None: + decoder_out_order_logits = torch.stack(decoder_out_order_logits, dim=1) + decoder_out_masks = torch.stack(decoder_out_masks, dim=1) + + return PPDocLayoutV3DecoderOutput( + last_hidden_state=hidden_states, + intermediate_hidden_states=intermediate, + intermediate_logits=intermediate_logits, + intermediate_reference_points=intermediate_reference_points, + decoder_out_order_logits=decoder_out_order_logits, + decoder_out_masks=decoder_out_masks, + ) + + +class PPDocLayoutV3FrozenBatchNorm2d(nn.Module): + """ + BatchNorm2d where the batch statistics and the affine parameters are fixed. + + Copy-paste from torchvision.misc.ops with added eps before rqsrt, without which any other models than + torchvision.models.resnet[18,34,50,101] produce nans. + """ + + def __init__(self, n): + super().__init__() + self.register_buffer("weight", torch.ones(n)) + self.register_buffer("bias", torch.zeros(n)) + self.register_buffer("running_mean", torch.zeros(n)) + self.register_buffer("running_var", torch.ones(n)) + + def _load_from_state_dict( + self, state_dict, prefix, local_metadata, strict, missing_keys, unexpected_keys, error_msgs + ): + num_batches_tracked_key = prefix + "num_batches_tracked" + if num_batches_tracked_key in state_dict: + del state_dict[num_batches_tracked_key] + + super()._load_from_state_dict( + state_dict, prefix, local_metadata, strict, missing_keys, unexpected_keys, error_msgs + ) + + def forward(self, x): + # move reshapes to the beginning + # to make it user-friendly + weight = self.weight.reshape(1, -1, 1, 1) + bias = self.bias.reshape(1, -1, 1, 1) + running_var = self.running_var.reshape(1, -1, 1, 1) + running_mean = self.running_mean.reshape(1, -1, 1, 1) + epsilon = 1e-5 + scale = weight * (running_var + epsilon).rsqrt() + bias = bias - running_mean * scale + return x * scale + bias + + +def replace_batch_norm(model): + r""" + Recursively replace all `torch.nn.BatchNorm2d` with `PPDocLayoutV3FrozenBatchNorm2d`. + + Args: + model (torch.nn.Module): + input model + """ + for name, module in model.named_children(): + if isinstance(module, nn.BatchNorm2d): + new_module = PPDocLayoutV3FrozenBatchNorm2d(module.num_features) + + if module.weight.device != torch.device("meta"): + new_module.weight.copy_(module.weight) + new_module.bias.copy_(module.bias) + new_module.running_mean.copy_(module.running_mean) + new_module.running_var.copy_(module.running_var) + + model._modules[name] = new_module + + if len(list(module.children())) > 0: + replace_batch_norm(module) + + +class PPDocLayoutV3ConvEncoder(nn.Module): + """ + Convolutional backbone using the modeling_pp_doclayout_v3_resnet.py. + + nn.BatchNorm2d layers are replaced by PPDocLayoutV3FrozenBatchNorm2d as defined above. + https://github.com/lyuwenyu/RT-DETR/blob/main/PPDocLayoutV3_pytorch/src/nn/backbone/presnet.py#L142 + """ + + def __init__(self, config): + super().__init__() + + backbone = load_backbone(config) + + if config.freeze_backbone_batch_norms: + # replace batch norm by frozen batch norm + with torch.no_grad(): + replace_batch_norm(backbone) + self.model = backbone + self.intermediate_channel_sizes = self.model.channels + + def forward(self, pixel_values: torch.Tensor, pixel_mask: torch.Tensor): + # send pixel_values through the model to get list of feature maps + features = self.model(pixel_values).feature_maps + + out = [] + for feature_map in features: + # downsample pixel_mask to match shape of corresponding feature_map + mask = nn.functional.interpolate(pixel_mask[None].float(), size=feature_map.shape[-2:]).to(torch.bool)[0] + out.append((feature_map, mask)) + return out + + +def get_contrastive_denoising_training_group( + targets, + num_classes, + num_queries, + class_embed, + num_denoising_queries=100, + label_noise_ratio=0.5, + box_noise_scale=1.0, +): + """ + Creates a contrastive denoising training group using ground-truth samples. It adds noise to labels and boxes. + + Args: + targets (`list[dict]`): + The target objects, each containing 'class_labels' and 'boxes' for objects in an image. + num_classes (`int`): + Total number of classes in the dataset. + num_queries (`int`): + Number of query slots in the transformer. + class_embed (`callable`): + A function or a model layer to embed class labels. + num_denoising_queries (`int`, *optional*, defaults to 100): + Number of denoising queries. + label_noise_ratio (`float`, *optional*, defaults to 0.5): + Ratio of noise applied to labels. + box_noise_scale (`float`, *optional*, defaults to 1.0): + Scale of noise applied to bounding boxes. + Returns: + `tuple` comprising various elements: + - **input_query_class** (`torch.FloatTensor`) -- + Class queries with applied label noise. + - **input_query_bbox** (`torch.FloatTensor`) -- + Bounding box queries with applied box noise. + - **attn_mask** (`torch.FloatTensor`) -- + Attention mask for separating denoising and reconstruction queries. + - **denoising_meta_values** (`dict`) -- + Metadata including denoising positive indices, number of groups, and split sizes. + """ + + if num_denoising_queries <= 0: + return None, None, None, None + + num_ground_truths = [len(t["class_labels"]) for t in targets] + device = targets[0]["class_labels"].device + + max_gt_num = max(num_ground_truths) + if max_gt_num == 0: + return None, None, None, None + + num_groups_denoising_queries = num_denoising_queries // max_gt_num + num_groups_denoising_queries = 1 if num_groups_denoising_queries == 0 else num_groups_denoising_queries + # pad gt to max_num of a batch + batch_size = len(num_ground_truths) + + input_query_class = torch.full([batch_size, max_gt_num], num_classes, dtype=torch.int32, device=device) + input_query_bbox = torch.zeros([batch_size, max_gt_num, 4], device=device) + pad_gt_mask = torch.zeros([batch_size, max_gt_num], dtype=torch.bool, device=device) + + for i in range(batch_size): + num_gt = num_ground_truths[i] + if num_gt > 0: + input_query_class[i, :num_gt] = targets[i]["class_labels"] + input_query_bbox[i, :num_gt] = targets[i]["boxes"] + pad_gt_mask[i, :num_gt] = 1 + # each group has positive and negative queries. + input_query_class = input_query_class.tile([1, 2 * num_groups_denoising_queries]) + input_query_bbox = input_query_bbox.tile([1, 2 * num_groups_denoising_queries, 1]) + pad_gt_mask = pad_gt_mask.tile([1, 2 * num_groups_denoising_queries]) + # positive and negative mask + negative_gt_mask = torch.zeros([batch_size, max_gt_num * 2, 1], device=device) + negative_gt_mask[:, max_gt_num:] = 1 + negative_gt_mask = negative_gt_mask.tile([1, num_groups_denoising_queries, 1]) + positive_gt_mask = 1 - negative_gt_mask + # contrastive denoising training positive index + positive_gt_mask = positive_gt_mask.squeeze(-1) * pad_gt_mask + denoise_positive_idx = torch.nonzero(positive_gt_mask)[:, 1] + denoise_positive_idx = torch.split( + denoise_positive_idx, [n * num_groups_denoising_queries for n in num_ground_truths] + ) + # total denoising queries + num_denoising_queries = torch_int(max_gt_num * 2 * num_groups_denoising_queries) + + if label_noise_ratio > 0: + mask = torch.rand_like(input_query_class, dtype=torch.float) < (label_noise_ratio * 0.5) + # randomly put a new one here + new_label = torch.randint_like(mask, 0, num_classes, dtype=input_query_class.dtype) + input_query_class = torch.where(mask & pad_gt_mask, new_label, input_query_class) + + if box_noise_scale > 0: + known_bbox = center_to_corners_format(input_query_bbox) + diff = torch.tile(input_query_bbox[..., 2:] * 0.5, [1, 1, 2]) * box_noise_scale + rand_sign = torch.randint_like(input_query_bbox, 0, 2) * 2.0 - 1.0 + rand_part = torch.rand_like(input_query_bbox) + rand_part = (rand_part + 1.0) * negative_gt_mask + rand_part * (1 - negative_gt_mask) + rand_part *= rand_sign + known_bbox += rand_part * diff + known_bbox.clip_(min=0.0, max=1.0) + input_query_bbox = corners_to_center_format(known_bbox) + input_query_bbox = inverse_sigmoid(input_query_bbox) + + input_query_class = class_embed(input_query_class) + + target_size = num_denoising_queries + num_queries + attn_mask = torch.full([target_size, target_size], 0, dtype=torch.float, device=device) + # match query cannot see the reconstruction + attn_mask[num_denoising_queries:, :num_denoising_queries] = -torch.inf + + # reconstructions cannot see each other + for i in range(num_groups_denoising_queries): + idx_block_start = max_gt_num * 2 * i + idx_block_end = max_gt_num * 2 * (i + 1) + attn_mask[idx_block_start:idx_block_end, :idx_block_start] = -torch.inf + attn_mask[idx_block_start:idx_block_end, idx_block_end:num_denoising_queries] = -torch.inf + + denoising_meta_values = { + "dn_positive_idx": denoise_positive_idx, + "dn_num_group": num_groups_denoising_queries, + "dn_num_split": [num_denoising_queries, num_queries], + } + + return input_query_class, input_query_bbox, attn_mask, denoising_meta_values + + +def mask_to_box_coordinate(mask, dtype): + mask = mask.bool() + + height, width = mask.shape[-2:] + + y_coords, x_coords = torch.meshgrid( + torch.arange(height, device=mask.device), torch.arange(width, device=mask.device), indexing="ij" + ) + x_coords = x_coords.to(dtype) + y_coords = y_coords.to(dtype) + + x_coords_masked = x_coords * mask + x_max = x_coords_masked.flatten(start_dim=-2).max(dim=-1).values + 1 + x_min = ( + torch.where(mask, x_coords_masked, torch.tensor(torch.finfo(dtype).max)) + .flatten(start_dim=-2) + .min(dim=-1) + .values + ) + + y_coords_masked = y_coords * mask + y_max = y_coords_masked.flatten(start_dim=-2).max(dim=-1).values + 1 + y_min = ( + torch.where(mask, y_coords_masked, torch.tensor(torch.finfo(dtype).max)) + .flatten(start_dim=-2) + .min(dim=-1) + .values + ) + + unnormalized_bbox = torch.stack([x_min, y_min, x_max, y_max], dim=-1) + + is_mask_non_empty = torch.any(mask, dim=(-2, -1)).unsqueeze(-1) + unnormalized_bbox = unnormalized_bbox * is_mask_non_empty + + norm_tensor = torch.tensor([width, height, width, height], device=mask.device, dtype=dtype) + normalized_bbox_xyxy = unnormalized_bbox / norm_tensor + + x_min_norm, y_min_norm, x_max_norm, y_max_norm = normalized_bbox_xyxy.unbind(dim=-1) + + center_x = (x_min_norm + x_max_norm) / 2 + center_y = (y_min_norm + y_max_norm) / 2 + box_width = x_max_norm - x_min_norm + box_height = y_max_norm - y_min_norm + + return torch.stack([center_x, center_y, box_width, box_height], dim=-1) + + +@auto_docstring( + custom_intro=""" + PP-DocLayoutV3 Model (consisting of a backbone and encoder-decoder) outputting raw hidden states without any head on top. + """ +) +class PPDocLayoutV3Model(PPDocLayoutV3PreTrainedModel): + _tied_weights_keys = { + "decoder.class_embed": "enc_score_head", + "decoder.bbox_embed": "enc_bbox_head", + } + + def __init__(self, config: PPDocLayoutV3Config): + super().__init__(config) + + # Create backbone + self.backbone = PPDocLayoutV3ConvEncoder(config) + intermediate_channel_sizes = self.backbone.intermediate_channel_sizes + + # Create encoder input projection layers + # https://github.com/lyuwenyu/RT-DETR/blob/94f5e16708329d2f2716426868ec89aa774af016/PPDocLayoutV3_pytorch/src/zoo/PPDocLayoutV3/hybrid_encoder.py#L212 + num_backbone_outs = len(intermediate_channel_sizes) + + encoder_input_proj_list = [] + for i in range(num_backbone_outs): + in_channels = intermediate_channel_sizes[i] + encoder_input_proj_list.append( + nn.Sequential( + nn.Conv2d(in_channels, config.encoder_hidden_dim, kernel_size=1, bias=False), + nn.BatchNorm2d(config.encoder_hidden_dim), + ) + ) + self.encoder_input_proj = nn.ModuleList(encoder_input_proj_list[1:]) + + # Create encoder + self.encoder = PPDocLayoutV3HybridEncoder(config) + + # denoising part + if config.num_denoising > 0: + self.denoising_class_embed = nn.Embedding( + config.num_labels + 1, config.d_model, padding_idx=config.num_labels + ) + + # decoder embedding + if config.learn_initial_query: + self.weight_embedding = nn.Embedding(config.num_queries, config.d_model) + + # encoder head + self.enc_output = nn.Sequential( + nn.Linear(config.d_model, config.d_model), + nn.LayerNorm(config.d_model, eps=config.layer_norm_eps), + ) + self.enc_score_head = nn.Linear(config.d_model, config.num_labels) + self.enc_bbox_head = PPDocLayoutV3MLPPredictionHead(config.d_model, config.d_model, 4, num_layers=3) + + # init encoder output anchors and valid_mask + if config.anchor_image_size: + self.anchors, self.valid_mask = self.generate_anchors(dtype=self.dtype) + + # Create decoder input projection layers + # https://github.com/lyuwenyu/RT-DETR/blob/94f5e16708329d2f2716426868ec89aa774af016/PPDocLayoutV3_pytorch/src/zoo/PPDocLayoutV3/PPDocLayoutV3_decoder.py#L412 + num_backbone_outs = len(config.decoder_in_channels) + decoder_input_proj_list = [] + for i in range(num_backbone_outs): + in_channels = config.decoder_in_channels[i] + decoder_input_proj_list.append( + nn.Sequential( + nn.Conv2d(in_channels, config.d_model, kernel_size=1, bias=False), + nn.BatchNorm2d(config.d_model, config.batch_norm_eps), + ) + ) + for _ in range(config.num_feature_levels - num_backbone_outs): + decoder_input_proj_list.append( + nn.Sequential( + nn.Conv2d(in_channels, config.d_model, kernel_size=3, stride=2, padding=1, bias=False), + nn.BatchNorm2d(config.d_model, config.batch_norm_eps), + ) + ) + in_channels = config.d_model + self.decoder_input_proj = nn.ModuleList(decoder_input_proj_list) + self.decoder = PPDocLayoutV3Decoder(config) + + self.decoder_order_head = nn.ModuleList( + [nn.Linear(config.d_model, config.d_model) for _ in range(config.decoder_layers)] + ) + self.decoder_global_pointer = PPDocLayoutV3GlobalPointer(config) + self.decoder_norm = nn.LayerNorm(config.d_model, eps=config.layer_norm_eps) + self.decoder.class_embed = nn.Linear(config.d_model, config.num_labels) + self.decoder.bbox_embed = PPDocLayoutV3MLPPredictionHead(config.d_model, config.d_model, 4, num_layers=3) + + self.mask_enhanced = config.mask_enhanced + self.mask_query_head = PPDocLayoutV3MLPPredictionHead( + config.d_model, config.d_model, config.num_prototypes, num_layers=3 + ) + + self.post_init() + + def freeze_backbone(self): + for param in self.backbone.parameters(): + param.requires_grad_(False) + + def unfreeze_backbone(self): + for param in self.backbone.parameters(): + param.requires_grad_(True) + + @compile_compatible_method_lru_cache(maxsize=32) + def generate_anchors(self, spatial_shapes=None, grid_size=0.05, device="cpu", dtype=torch.float32): + if spatial_shapes is None: + spatial_shapes = [ + [int(self.config.anchor_image_size[0] / s), int(self.config.anchor_image_size[1] / s)] + for s in self.config.feat_strides + ] + anchors = [] + for level, (height, width) in enumerate(spatial_shapes): + grid_y, grid_x = torch.meshgrid( + torch.arange(end=height, device=device).to(dtype), + torch.arange(end=width, device=device).to(dtype), + indexing="ij", + ) + grid_xy = torch.stack([grid_x, grid_y], -1) + grid_xy = grid_xy.unsqueeze(0) + 0.5 + grid_xy[..., 0] /= width + grid_xy[..., 1] /= height + wh = torch.ones_like(grid_xy) * grid_size * (2.0**level) + anchors.append(torch.concat([grid_xy, wh], -1).reshape(-1, height * width, 4)) + # define the valid range for anchor coordinates + eps = 1e-2 + anchors = torch.concat(anchors, 1) + valid_mask = ((anchors > eps) * (anchors < 1 - eps)).all(-1, keepdim=True) + anchors = torch.log(anchors / (1 - anchors)) + anchors = torch.where(valid_mask, anchors, torch.tensor(torch.finfo(dtype).max, dtype=dtype, device=device)) + + return anchors, valid_mask + + @auto_docstring + @can_return_tuple + def forward( + self, + pixel_values: torch.FloatTensor, + pixel_mask: torch.LongTensor | None = None, + encoder_outputs: torch.FloatTensor | None = None, + labels: list[dict] | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.FloatTensor] | PPDocLayoutV3ModelOutput: + r""" + inputs_embeds (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*): + Optionally, instead of passing the flattened feature map (output of the backbone + projection layer), you + can choose to directly pass a flattened representation of an image. + decoder_inputs_embeds (`torch.FloatTensor` of shape `(batch_size, num_queries, hidden_size)`, *optional*): + Optionally, instead of initializing the queries with a tensor of zeros, you can choose to directly pass an + embedded representation. + labels (`list[Dict]` of len `(batch_size,)`, *optional*): + Labels for computing the bipartite matching loss. List of dicts, each dictionary containing at least the + following 2 keys: 'class_labels' and 'boxes' (the class labels and bounding boxes of an image in the batch + respectively). The class labels themselves should be a `torch.LongTensor` of len `(number of bounding boxes + in the image,)` and the boxes a `torch.FloatTensor` of shape `(number of bounding boxes in the image, 4)`. + + Examples: + + ```python + >>> from transformers import AutoImageProcessor, PPDocLayoutV2Model + >>> from PIL import Image + >>> import requests + + >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg" + >>> image = Image.open(requests.get(url, stream=True).raw) + + >>> image_processor = AutoImageProcessor.from_pretrained("PekingU/PPDocLayoutV2_r50vd") + >>> model = PPDocLayoutV2Model.from_pretrained("PekingU/PPDocLayoutV2_r50vd") + + >>> inputs = image_processor(images=image, return_tensors="pt") + + >>> outputs = model(**inputs) + + >>> last_hidden_states = outputs.last_hidden_state + >>> list(last_hidden_states.shape) + [1, 300, 256] + ```""" + batch_size, num_channels, height, width = pixel_values.shape + device = pixel_values.device + + if pixel_mask is None: + pixel_mask = torch.ones(((batch_size, height, width)), device=device) + + features = self.backbone(pixel_values, pixel_mask) + x4_feat = features.pop(0) + proj_feats = [self.encoder_input_proj[level](source) for level, (source, mask) in enumerate(features)] + + if encoder_outputs is None: + encoder_outputs = self.encoder( + proj_feats, + x4_feat, + **kwargs, + ) + # If the user passed a tuple for encoder_outputs, we wrap it in a PPDocLayoutV3HybridEncoderOutput when return_dict=True + elif not isinstance(encoder_outputs, PPDocLayoutV3HybridEncoderOutput): + encoder_outputs = PPDocLayoutV3HybridEncoderOutput( + last_hidden_state=encoder_outputs[0], + hidden_states=encoder_outputs[1] if len(encoder_outputs) > 1 else None, + attentions=encoder_outputs[2] if len(encoder_outputs) > 2 else None, + mask_feat=encoder_outputs[-1], + ) + + # Equivalent to def _get_encoder_input + # https://github.com/lyuwenyu/RT-DETR/blob/94f5e16708329d2f2716426868ec89aa774af016/rtdetr_pytorch/src/zoo/rtdetr/rtdetr_decoder.py#L412 + sources = [] + for level, source in enumerate(encoder_outputs.last_hidden_state): + sources.append(self.decoder_input_proj[level](source)) + + # Lowest resolution feature maps are obtained via 3x3 stride 2 convolutions on the final stage + if self.config.num_feature_levels > len(sources): + _len_sources = len(sources) + sources.append(self.decoder_input_proj[_len_sources](encoder_outputs.last_hidden_state[-1])) + for i in range(_len_sources + 1, self.config.num_feature_levels): + sources.append(self.decoder_input_proj[i](encoder_outputs.last_hidden_state[-1])) + + # Prepare encoder inputs (by flattening) + source_flatten = [] + spatial_shapes_list = [] + spatial_shapes = torch.empty((len(sources), 2), device=device, dtype=torch.long) + for level, source in enumerate(sources): + height, width = source.shape[-2:] + spatial_shapes[level, 0] = height + spatial_shapes[level, 1] = width + spatial_shapes_list.append((height, width)) + source = source.flatten(2).transpose(1, 2) + source_flatten.append(source) + source_flatten = torch.cat(source_flatten, 1) + level_start_index = torch.cat((spatial_shapes.new_zeros((1,)), spatial_shapes.prod(1).cumsum(0)[:-1])) + + # prepare denoising training + if self.training and self.config.num_denoising > 0 and labels is not None: + ( + denoising_class, + denoising_bbox_unact, + attention_mask, + denoising_meta_values, + ) = get_contrastive_denoising_training_group( + targets=labels, + num_classes=self.config.num_labels, + num_queries=self.config.num_queries, + class_embed=self.denoising_class_embed, + num_denoising_queries=self.config.num_denoising, + label_noise_ratio=self.config.label_noise_ratio, + box_noise_scale=self.config.box_noise_scale, + ) + else: + denoising_class, denoising_bbox_unact, attention_mask, denoising_meta_values = None, None, None, None + + batch_size = len(source_flatten) + device = source_flatten.device + dtype = source_flatten.dtype + + # prepare input for decoder + if self.training or self.config.anchor_image_size is None: + # Pass spatial_shapes as tuple to make it hashable and make sure + # lru_cache is working for generate_anchors() + spatial_shapes_tuple = tuple(spatial_shapes_list) + anchors, valid_mask = self.generate_anchors(spatial_shapes_tuple, device=device, dtype=dtype) + else: + anchors, valid_mask = self.anchors, self.valid_mask + anchors, valid_mask = anchors.to(device, dtype), valid_mask.to(device, dtype) + + # use the valid_mask to selectively retain values in the feature map where the mask is `True` + memory = valid_mask.to(source_flatten.dtype) * source_flatten + + output_memory = self.enc_output(memory) + + enc_outputs_class = self.enc_score_head(output_memory) + enc_outputs_coord_logits = self.enc_bbox_head(output_memory) + anchors + + _, topk_ind = torch.topk(enc_outputs_class.max(-1).values, self.config.num_queries, dim=1) + + reference_points_unact = enc_outputs_coord_logits.gather( + dim=1, index=topk_ind.unsqueeze(-1).repeat(1, 1, enc_outputs_coord_logits.shape[-1]) + ) + + # _get_pred_class_and_mask + batch_ind = torch.arange(memory.shape[0], device=output_memory.device).unsqueeze(1) + target = output_memory[batch_ind, topk_ind] + out_query = self.decoder_norm(target) + mask_query_embed = self.mask_query_head(out_query) + batch_size, mask_dim, _ = mask_query_embed.shape + + enc_topk_bboxes = F.sigmoid(reference_points_unact) + + enc_topk_logits = enc_outputs_class.gather( + dim=1, index=topk_ind.unsqueeze(-1).repeat(1, 1, enc_outputs_class.shape[-1]) + ) + + # extract region features + if self.config.learn_initial_query: + target = self.weight_embedding.tile([batch_size, 1, 1]) + else: + target = output_memory.gather(dim=1, index=topk_ind.unsqueeze(-1).repeat(1, 1, output_memory.shape[-1])) + target = target.detach() + + if denoising_class is not None: + target = torch.concat([denoising_class, target], 1) + + if self.mask_enhanced: + _, _, mask_h, mask_w = encoder_outputs.mask_feat.shape + enc_out_masks = torch.bmm(mask_query_embed, encoder_outputs.mask_feat.flatten(start_dim=2)).reshape( + batch_size, mask_dim, mask_h, mask_w + ) + reference_points = mask_to_box_coordinate(enc_out_masks > 0, dtype=reference_points_unact.dtype) + reference_points_unact = inverse_sigmoid(reference_points) + + if denoising_bbox_unact is not None: + reference_points_unact = torch.concat([denoising_bbox_unact, reference_points_unact], 1) + + init_reference_points = reference_points_unact.detach() + + # decoder + decoder_outputs = self.decoder( + inputs_embeds=target, + encoder_hidden_states=source_flatten, + encoder_attention_mask=attention_mask, + reference_points=init_reference_points, + spatial_shapes=spatial_shapes, + spatial_shapes_list=spatial_shapes_list, + level_start_index=level_start_index, + order_head=self.decoder_order_head, + global_pointer=self.decoder_global_pointer, + mask_query_head=self.mask_query_head, + norm=self.decoder_norm, + mask_feat=encoder_outputs.mask_feat, + **kwargs, + ) + + return PPDocLayoutV3ModelOutput( + last_hidden_state=decoder_outputs.last_hidden_state, + intermediate_hidden_states=decoder_outputs.intermediate_hidden_states, + intermediate_logits=decoder_outputs.intermediate_logits, + intermediate_reference_points=decoder_outputs.intermediate_reference_points, + intermediate_predicted_corners=decoder_outputs.intermediate_predicted_corners, + initial_reference_points=decoder_outputs.initial_reference_points, + decoder_hidden_states=decoder_outputs.hidden_states, + decoder_attentions=decoder_outputs.attentions, + cross_attentions=decoder_outputs.cross_attentions, + out_order_logits=decoder_outputs.decoder_out_order_logits, + out_masks=decoder_outputs.decoder_out_masks, + encoder_last_hidden_state=encoder_outputs.last_hidden_state, + encoder_hidden_states=encoder_outputs.hidden_states, + encoder_attentions=encoder_outputs.attentions, + init_reference_points=init_reference_points, + enc_topk_logits=enc_topk_logits, + enc_topk_bboxes=enc_topk_bboxes, + enc_outputs_class=enc_outputs_class, + enc_outputs_coord_logits=enc_outputs_coord_logits, + denoising_meta_values=denoising_meta_values, + ) + + +@dataclass +@auto_docstring +class PPDocLayoutV3HybridEncoderOutput(BaseModelOutput): + r""" + mask_feat (`torch.FloatTensor` of shape `(batch_size, config.num_queries, 200, 200)`): + Mask features for each query in the batch. + """ + + mask_feat: torch.FloatTensor = None + + +@dataclass +@auto_docstring +class PPDocLayoutV3ForObjectDetectionOutput(ModelOutput): + r""" + logits (`torch.FloatTensor` of shape `(batch_size, num_queries, num_classes + 1)`): + Classification logits (including no-object) for all queries. + pred_boxes (`torch.FloatTensor` of shape `(batch_size, num_queries, 4)`): + Normalized boxes coordinates for all queries, represented as (center_x, center_y, width, height). These + values are normalized in [0, 1], relative to the size of each individual image in the batch (disregarding + possible padding). You can use [`~PPDocLayoutV3ImageProcessorFast.post_process_object_detection`] to retrieve the + unnormalized (absolute) bounding boxes. + order_logits (`tuple` of `torch.FloatTensor` of shape `(batch_size, num_queries, num_queries)`): + Order logits of the final layer of the decoder. + out_masks (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, height, width)`): + Masks of the final layer of the decoder. + last_hidden_state (`torch.FloatTensor` of shape `(batch_size, num_queries, hidden_size)`): + Sequence of hidden-states at the output of the last layer of the decoder of the model. + intermediate_hidden_states (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, hidden_size)`): + Stacked intermediate hidden states (output of each layer of the decoder). + intermediate_logits (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, config.num_labels)`): + Stacked intermediate logits (logits of each layer of the decoder). + intermediate_reference_points (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, 4)`): + Stacked intermediate reference points (reference points of each layer of the decoder). + intermediate_predicted_corners (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, 4)`): + Stacked intermediate predicted corners (predicted corners of each layer of the decoder). + initial_reference_points (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, 4)`): + Stacked initial reference points (initial reference points of each layer of the decoder). + init_reference_points (`torch.FloatTensor` of shape `(batch_size, num_queries, 4)`): + Initial reference points sent through the Transformer decoder. + enc_topk_logits (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.num_labels)`, *optional*, returned when `config.with_box_refine=True` and `config.two_stage=True`): + Logits of predicted bounding boxes coordinates in the encoder. + enc_topk_bboxes (`torch.FloatTensor` of shape `(batch_size, sequence_length, 4)`, *optional*, returned when `config.with_box_refine=True` and `config.two_stage=True`): + Logits of predicted bounding boxes coordinates in the encoder. + enc_outputs_class (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.num_labels)`, *optional*, returned when `config.with_box_refine=True` and `config.two_stage=True`): + Predicted bounding boxes scores where the top `config.two_stage_num_proposals` scoring bounding boxes are + picked as region proposals in the first stage. Output of bounding box binary classification (i.e. + foreground and background). + enc_outputs_coord_logits (`torch.FloatTensor` of shape `(batch_size, sequence_length, 4)`, *optional*, returned when `config.with_box_refine=True` and `config.two_stage=True`): + Logits of predicted bounding boxes coordinates in the first stage. + denoising_meta_values (`dict`): + Extra dictionary for the denoising related values + """ + + logits: torch.FloatTensor | None = None + pred_boxes: torch.FloatTensor | None = None + order_logits: torch.FloatTensor | None = None + out_masks: torch.FloatTensor | None = None + last_hidden_state: torch.FloatTensor | None = None + intermediate_hidden_states: torch.FloatTensor | None = None + intermediate_logits: torch.FloatTensor | None = None + intermediate_reference_points: torch.FloatTensor | None = None + intermediate_predicted_corners: torch.FloatTensor | None = None + initial_reference_points: torch.FloatTensor | None = None + decoder_hidden_states: tuple[torch.FloatTensor] | None = None + decoder_attentions: tuple[torch.FloatTensor] | None = None + cross_attentions: tuple[torch.FloatTensor] | None = None + encoder_last_hidden_state: torch.FloatTensor | None = None + encoder_hidden_states: tuple[torch.FloatTensor] | None = None + encoder_attentions: tuple[torch.FloatTensor] | None = None + init_reference_points: tuple[torch.FloatTensor] | None = None + enc_topk_logits: torch.FloatTensor | None = None + enc_topk_bboxes: torch.FloatTensor | None = None + enc_outputs_class: torch.FloatTensor | None = None + enc_outputs_coord_logits: torch.FloatTensor | None = None + denoising_meta_values: dict | None = None + + +@auto_docstring( + custom_intro=""" + PP-DocLayoutV3 Model (consisting of a backbone and encoder-decoder) outputs bounding boxes and logits sorted according to reading order, + which are further decoded into scores and classes. + """ +) +class PPDocLayoutV3ForObjectDetection(PPDocLayoutV3PreTrainedModel): + # When using clones, all layers > 0 will be clones, but layer 0 *is* required + # We can't initialize the model on meta device as some weights are modified during the initialization + _no_split_modules = None + _keys_to_ignore_on_load_missing = ["num_batches_tracked", "rel_pos_y_bias", "rel_pos_x_bias"] + + def __init__(self, config: PPDocLayoutV3Config): + super().__init__(config) + self.model = PPDocLayoutV3Model(config) + + self.model.denoising_class_embed = nn.Embedding(config.num_labels, config.d_model) + self.num_queries = config.num_queries + # if two-stage, the last class_embed and bbox_embed is for region proposal generation + self.post_init() + + def _set_aux_loss(self, outputs_class, outputs_coord): + return [{"logits": a, "pred_boxes": b} for a, b in zip(outputs_class, outputs_coord)] + + @auto_docstring + @can_return_tuple + def forward( + self, + pixel_values: torch.FloatTensor, + pixel_mask: torch.LongTensor | None = None, + encoder_outputs: torch.FloatTensor | None = None, + labels: list[dict] | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.FloatTensor] | PPDocLayoutV3ForObjectDetectionOutput: + r""" + inputs_embeds (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*): + Optionally, instead of passing the flattened feature map (output of the backbone + projection layer), you + can choose to directly pass a flattened representation of an image. + decoder_inputs_embeds (`torch.FloatTensor` of shape `(batch_size, num_queries, hidden_size)`, *optional*): + Optionally, instead of initializing the queries with a tensor of zeros, you can choose to directly pass an + embedded representation. + labels (`list[Dict]` of len `(batch_size,)`, *optional*): + Labels for computing the bipartite matching loss. List of dicts, each dictionary containing at least the + following 2 keys: 'class_labels' and 'boxes' (the class labels and bounding boxes of an image in the batch + respectively). The class labels themselves should be a `torch.LongTensor` of len `(number of bounding boxes + in the image,)` and the boxes a `torch.FloatTensor` of shape `(number of bounding boxes in the image, 4)`. + + Examples: + + ```python + >>> from transformers import AutoModelForObjectDetection, AutoImageProcessor + >>> from PIL import Image + >>> import requests + >>> import torch + + >>> url = "https://paddle-model-ecology.bj.bcebos.com/paddlex/imgs/demo_image/layout_demo.jpg" + >>> image = Image.open(requests.get(url, stream=True).raw) + + >>> model_path = "PaddlePaddle/PP-DocLayoutV3_safetensors" + >>> image_processor = AutoImageProcessor.from_pretrained(model_path) + >>> model = AutoModelForObjectDetection.from_pretrained(model_path) + + >>> # prepare image for the model + >>> inputs = image_processor(images=[image], return_tensors="pt") + + >>> # forward pass + >>> outputs = model(**inputs) + + >>> # convert outputs (bounding boxes and class logits) to Pascal VOC format (xmin, ymin, xmax, ymax) + >>> results = image_processor.post_process_object_detection(outputs, target_sizes=torch.tensor([image.size[::-1]])) + + >>> # print outputs + >>> for result in results: + ... for idx, (score, label_id, box) in enumerate(zip(result["scores"], result["labels"], result["boxes"])): + ... score, label = score.item(), label_id.item() + ... box = [round(i, 2) for i in box.tolist()] + ... print(f"Order {idx + 1}: {model.config.id2label[label]}: {score:.2f} {box}") + Order 1: text: 0.99 [334.95, 184.78, 897.25, 654.83] + Order 2: paragraph_title: 0.97 [337.28, 683.92, 869.16, 798.35] + Order 3: text: 0.99 [335.75, 842.82, 892.13, 1454.32] + Order 4: text: 0.99 [920.18, 185.28, 1476.38, 464.49] + Order 5: text: 0.98 [920.47, 483.68, 1480.63, 765.72] + Order 6: text: 0.98 [920.62, 846.8, 1482.09, 1220.67] + Order 7: text: 0.97 [920.92, 1239.41, 1469.55, 1378.02] + Order 8: footnote: 0.86 [335.03, 1614.68, 1483.33, 1731.73] + Order 9: footnote: 0.83 [334.64, 1756.74, 1471.78, 1845.69] + Order 10: text: 0.81 [336.8, 1910.52, 661.64, 1939.92] + Order 11: footnote: 0.96 [336.24, 2114.42, 1450.14, 2172.12] + Order 12: number: 0.88 [106.0, 2257.5, 135.84, 2282.18] + Order 13: footer: 0.93 [338.4, 2255.52, 986.15, 2284.37] + ```""" + outputs = self.model( + pixel_values, + pixel_mask=pixel_mask, + encoder_outputs=encoder_outputs, + labels=labels, + **kwargs, + ) + + intermediate_logits = outputs.intermediate_logits + intermediate_reference_points = outputs.intermediate_reference_points + order_logits = outputs.out_order_logits + out_masks = outputs.out_masks + + pred_boxes = intermediate_reference_points[:, -1] + logits = intermediate_logits[:, -1] + order_logits = order_logits[:, -1] + out_masks = out_masks[:, -1] + + if labels is not None: + raise ValueError("PPDocLayoutV3ForObjectDetection does not support training") + + return PPDocLayoutV3ForObjectDetectionOutput( + logits=logits, + pred_boxes=pred_boxes, + order_logits=order_logits, + out_masks=out_masks, + last_hidden_state=outputs.last_hidden_state, + intermediate_hidden_states=outputs.intermediate_hidden_states, + intermediate_logits=outputs.intermediate_logits, + intermediate_reference_points=outputs.intermediate_reference_points, + intermediate_predicted_corners=outputs.intermediate_predicted_corners, + initial_reference_points=outputs.initial_reference_points, + decoder_hidden_states=outputs.decoder_hidden_states, + decoder_attentions=outputs.decoder_attentions, + cross_attentions=outputs.cross_attentions, + encoder_last_hidden_state=outputs.encoder_last_hidden_state, + encoder_hidden_states=outputs.encoder_hidden_states, + encoder_attentions=outputs.encoder_attentions, + init_reference_points=outputs.init_reference_points, + enc_topk_logits=outputs.enc_topk_logits, + enc_topk_bboxes=outputs.enc_topk_bboxes, + enc_outputs_class=outputs.enc_outputs_class, + enc_outputs_coord_logits=outputs.enc_outputs_coord_logits, + denoising_meta_values=outputs.denoising_meta_values, + ) + + +__all__ = ["PPDocLayoutV3ForObjectDetection", "PPDocLayoutV3Model", "PPDocLayoutV3PreTrainedModel"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pp_doclayout_v3/modular_pp_doclayout_v3.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pp_doclayout_v3/modular_pp_doclayout_v3.py new file mode 100644 index 0000000000000000000000000000000000000000..a4b2536c4096bb05e1d3ad7173484357831b0471 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pp_doclayout_v3/modular_pp_doclayout_v3.py @@ -0,0 +1,1546 @@ +# Copyright 2026 The PaddlePaddle Team and The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import math +from dataclasses import dataclass +from typing import Optional + +import numpy as np +import torch +import torch.nn.functional as F +import torchvision.transforms.v2.functional as tvF +from torch import nn + +from ... import initialization as init +from ...backbone_utils import consolidate_backbone_kwargs_to_config +from ...configuration_utils import PreTrainedConfig +from ...image_processing_utils_fast import ( + BaseImageProcessorFast, + BatchFeature, +) +from ...image_transforms import ( + group_images_by_shape, + reorder_images, +) +from ...image_utils import PILImageResampling, SizeDict +from ...modeling_outputs import BaseModelOutput +from ...processing_utils import Unpack +from ...utils import ( + ModelOutput, + TransformersKwargs, + auto_docstring, + is_cv2_available, + logging, + requires_backends, +) +from ...utils.generic import TensorType, can_return_tuple +from ..auto import AutoConfig +from ..resnet.modeling_resnet import ResNetConvLayer +from ..rt_detr.modeling_rt_detr import ( + RTDetrDecoder, + RTDetrDecoderOutput, + RTDetrForObjectDetection, + RTDetrHybridEncoder, + RTDetrMLPPredictionHead, + RTDetrModel, + RTDetrModelOutput, + RTDetrMultiscaleDeformableAttention, + RTDetrPreTrainedModel, + get_contrastive_denoising_training_group, + inverse_sigmoid, +) + + +if is_cv2_available(): + import cv2 + + +logger = logging.get_logger(__name__) + + +class PPDocLayoutV3Config(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`PP-DocLayoutV3`]. It is used to instantiate a + PP-DocLayoutV3 model according to the specified arguments, defining the model architecture. Instantiating a configuration + with the defaults will yield a similar configuration to that of the PP-DocLayoutV3 + [PaddlePaddle/PP-DocLayoutV3_safetensors](https://huggingface.co/PaddlePaddle/PP-DocLayoutV3_safetensors) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + initializer_range (`float`, *optional*, defaults to 0.01): + The standard deviation of the truncated_normal_initializer for initializing all weight matrices. + initializer_bias_prior_prob (`float`, *optional*): + The prior probability used by the bias initializer to initialize biases for `enc_score_head` and `class_embed`. + If `None`, `prior_prob` computed as `prior_prob = 1 / (num_labels + 1)` while initializing model weights. + layer_norm_eps (`float`, *optional*, defaults to 1e-05): + The epsilon used by the layer normalization layers. + batch_norm_eps (`float`, *optional*, defaults to 1e-05): + The epsilon used by the batch normalization layers. + tie_word_embeddings (`bool`, *optional*, defaults to `True`): + Whether the model's input and output word embeddings should be tied. + backbone_config (`Union[dict, "PreTrainedConfig"]`, *optional*): + The configuration of the backbone model. + freeze_backbone_batch_norms (`bool`, *optional*, defaults to `True`): + Whether to freeze the batch normalization layers in the backbone. + encoder_hidden_dim (`int`, *optional*, defaults to 256): + Dimension of the layers in hybrid encoder. + encoder_in_channels (`list`, *optional*, defaults to `[512, 1024, 2048]`): + Multi level features input for encoder. + feat_strides (`list[int]`, *optional*, defaults to `[8, 16, 32]`): + Strides used in each feature map. + encoder_layers (`int`, *optional*, defaults to 1): + Total of layers to be used by the encoder. + encoder_ffn_dim (`int`, *optional*, defaults to 1024): + Dimension of the "intermediate" (often named feed-forward) layer in decoder. + encoder_attention_heads (`int`, *optional*, defaults to 8): + Number of attention heads for each attention layer in the Transformer encoder. + dropout (`float`, *optional*, defaults to 0.0): + The ratio for all dropout layers. + activation_dropout (`float`, *optional*, defaults to 0.0): + The dropout ratio for activations inside the fully connected layer. + encode_proj_layers (`list[int]`, *optional*, defaults to `[2]`): + Indexes of the projected layers to be used in the encoder. + positional_encoding_temperature (`int`, *optional*, defaults to 10000): + The temperature parameter used to create the positional encodings. + encoder_activation_function (`str`, *optional*, defaults to `"gelu"`): + The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`, + `"relu"`, `"silu"` and `"gelu_new"` are supported. + activation_function (`str`, *optional*, defaults to `"silu"`): + The non-linear activation function (function or string) in the general layer. If string, `"gelu"`, + `"relu"`, `"silu"` and `"gelu_new"` are supported. + eval_size (`tuple[int, int]`, *optional*): + Height and width used to computes the effective height and width of the position embeddings after taking + into account the stride. + normalize_before (`bool`, *optional*, defaults to `False`): + Determine whether to apply layer normalization in the transformer encoder layer before self-attention and + feed-forward modules. + hidden_expansion (`float`, *optional*, defaults to 1.0): + Expansion ratio to enlarge the dimension size of RepVGGBlock and CSPRepLayer. + mask_feature_channels (`list[int]`, *optional*, defaults to `[64, 64]`): + The channels of the multi-level features for mask enhancement. + x4_feat_dim (`int`, *optional*, defaults to 128): + The dimension of the x4 feature map. + d_model (`int`, *optional*, defaults to 256): + Dimension of the layers exclude hybrid encoder. + num_prototypes (`int`, *optional*, defaults to 32): + Dimension of the layers exclude mask query head. + label_noise_ratio (`float`, *optional*, defaults to 0.4): + The fraction of denoising labels to which random noise should be added. + box_noise_scale (`float`, *optional*, defaults to 0.4): + Scale or magnitude of noise to be added to the bounding boxes. + mask_enhanced (`bool`, *optional*, defaults to `True`): + Whether to use enhanced masked attention. + num_queries (`int`, *optional*, defaults to 300): + Number of object queries. + decoder_in_channels (`list`, *optional*, defaults to `[256, 256, 256]`): + Multi level features dimension for decoder + decoder_ffn_dim (`int`, *optional*, defaults to 1024): + Dimension of the "intermediate" (often named feed-forward) layer in decoder. + num_feature_levels (`int`, *optional*, defaults to 3): + The number of input feature levels. + decoder_n_points (`int`, *optional*, defaults to 4): + The number of sampled keys in each feature level for each attention head in the decoder. + decoder_layers (`int`, *optional*, defaults to 6): + Number of decoder layers. + decoder_attention_heads (`int`, *optional*, defaults to 8): + Number of attention heads for each attention layer in the Transformer decoder. + decoder_activation_function (`str`, *optional*, defaults to `"relu"`): + The non-linear activation function (function or string) in the decoder. If string, `"gelu"`, + `"relu"`, `"silu"` and `"gelu_new"` are supported. + attention_dropout (`float`, *optional*, defaults to 0.0): + The dropout ratio for the attention probabilities. + num_denoising (`int`, *optional*, defaults to 100): + The total number of denoising tasks or queries to be used for contrastive denoising. + learn_initial_query (`bool`, *optional*, defaults to `False`): + Indicates whether the initial query embeddings for the decoder should be learned during training + anchor_image_size (`tuple[int, int]`, *optional*): + Height and width of the input image used during evaluation to generate the bounding box anchors. If None, automatic generate anchor is applied. + disable_custom_kernels (`bool`, *optional*, defaults to `True`): + Whether to disable custom kernels. + is_encoder_decoder (`bool`, *optional*, defaults to `True`): + Whether the architecture has an encoder decoder structure. + global_pointer_head_size (`int`, *optional*, defaults to 64): + The size of the global pointer head. + gp_dropout_value (`float`, *optional*, defaults to 0.1): + The dropout probability in the global pointer head. + Examples: + + ```python + >>> from transformers import PPDocLayoutV3Config, PPDocLayoutV3ForObjectDetection + + >>> # Initializing a PP-DocLayoutV3 configuration + >>> configuration = PPDocLayoutV3Config() + + >>> # Initializing a model (with random weights) from the configuration + >>> model = PPDocLayoutV3ForObjectDetection(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "pp_doclayout_v3" + sub_configs = {"backbone_config": AutoConfig} + + layer_types = ("basic", "bottleneck") + attribute_map = { + "hidden_size": "d_model", + "num_attention_heads": "encoder_attention_heads", + } + + def __init__( + self, + initializer_range=0.01, + initializer_bias_prior_prob=None, + layer_norm_eps=1e-5, + batch_norm_eps=1e-5, + tie_word_embeddings=True, + # backbone + backbone_config=None, + freeze_backbone_batch_norms=True, + # encoder PPDocLayoutV3HybridEncoder + encoder_hidden_dim=256, + encoder_in_channels=[512, 1024, 2048], + feat_strides=[8, 16, 32], + encoder_layers=1, + encoder_ffn_dim=1024, + encoder_attention_heads=8, + dropout=0.0, + activation_dropout=0.0, + encode_proj_layers=[2], + positional_encoding_temperature=10000, + encoder_activation_function="gelu", + activation_function="silu", + eval_size=None, + normalize_before=False, + hidden_expansion=1.0, + mask_feature_channels=[64, 64], + x4_feat_dim=128, + # decoder PPDocLayoutV3Transformer + d_model=256, + num_prototypes=32, + label_noise_ratio=0.4, + box_noise_scale=0.4, + mask_enhanced=True, + num_queries=300, + decoder_in_channels=[256, 256, 256], + decoder_ffn_dim=1024, + num_feature_levels=3, + decoder_n_points=4, + decoder_layers=6, + decoder_attention_heads=8, + decoder_activation_function="relu", + attention_dropout=0.0, + num_denoising=100, + learn_initial_query=False, + anchor_image_size=None, + disable_custom_kernels=True, + is_encoder_decoder=True, + global_pointer_head_size=64, + gp_dropout_value=0.1, + **kwargs, + ): + self.initializer_range = initializer_range + self.initializer_bias_prior_prob = initializer_bias_prior_prob + self.layer_norm_eps = layer_norm_eps + self.batch_norm_eps = batch_norm_eps + self.tie_word_embeddings = tie_word_embeddings + + backbone_config, kwargs = consolidate_backbone_kwargs_to_config( + backbone_config=backbone_config, + default_config_type="hgnet_v2", + default_config_kwargs={ + "arch": "L", + "return_idx": [0, 1, 2, 3], + "freeze_stem_only": True, + "freeze_at": 0, + "freeze_norm": True, + "lr_mult_list": [0, 0.05, 0.05, 0.05, 0.05], + "out_features": ["stage1", "stage2", "stage3", "stage4"], + }, + **kwargs, + ) + + self.backbone_config = backbone_config + self.freeze_backbone_batch_norms = freeze_backbone_batch_norms + + # ---- encoder ---- + self.encoder_hidden_dim = encoder_hidden_dim + self.encoder_in_channels = list(encoder_in_channels) + self.feat_strides = list(feat_strides) + self.encoder_layers = encoder_layers + self.encoder_ffn_dim = encoder_ffn_dim + self.encoder_attention_heads = encoder_attention_heads + self.dropout = dropout + self.activation_dropout = activation_dropout + self.encode_proj_layers = list(encode_proj_layers) + self.positional_encoding_temperature = positional_encoding_temperature + self.encoder_activation_function = encoder_activation_function + self.activation_function = activation_function + self.eval_size = list(eval_size) if eval_size is not None else None + self.normalize_before = normalize_before + self.hidden_expansion = hidden_expansion + self.mask_feature_channels = mask_feature_channels + self.x4_feat_dim = x4_feat_dim + + # ---- decoder ---- + self.d_model = d_model + self.num_queries = num_queries + self.num_prototypes = num_prototypes + self.decoder_in_channels = list(decoder_in_channels) + self.decoder_ffn_dim = decoder_ffn_dim + self.num_feature_levels = num_feature_levels + self.decoder_n_points = decoder_n_points + self.decoder_layers = decoder_layers + self.decoder_attention_heads = decoder_attention_heads + self.decoder_activation_function = decoder_activation_function + self.attention_dropout = attention_dropout + self.num_denoising = num_denoising + self.label_noise_ratio = label_noise_ratio + self.mask_enhanced = mask_enhanced + self.box_noise_scale = box_noise_scale + self.learn_initial_query = learn_initial_query + self.anchor_image_size = list(anchor_image_size) if anchor_image_size is not None else None + self.disable_custom_kernels = disable_custom_kernels + self.global_pointer_head_size = global_pointer_head_size + self.gp_dropout_value = gp_dropout_value + + super().__init__(is_encoder_decoder=is_encoder_decoder, **kwargs) + + +@auto_docstring +class PPDocLayoutV3ImageProcessorFast(BaseImageProcessorFast): + resample = PILImageResampling.BICUBIC + image_mean = [0, 0, 0] + image_std = [1, 1, 1] + size = {"height": 800, "width": 800} + do_resize = True + do_rescale = True + do_normalize = True + + # We require `self.resize(..., antialias=False)` to approximate the output of `cv2.resize` + def _preprocess( + self, + images: list["torch.Tensor"], + do_resize: bool, + size: SizeDict, + interpolation: Optional["tvF.InterpolationMode"], + do_center_crop: bool, + crop_size: SizeDict, + do_rescale: bool, + rescale_factor: float, + do_normalize: bool, + image_mean: float | list[float] | None, + image_std: float | list[float] | None, + do_pad: bool | None, + pad_size: SizeDict | None, + disable_grouping: bool | None, + return_tensors: str | TensorType | None, + **kwargs, + ) -> BatchFeature: + # Group images by size for batched resizing + grouped_images, grouped_images_index = group_images_by_shape(images, disable_grouping=disable_grouping) + resized_images_grouped = {} + for shape, stacked_images in grouped_images.items(): + if do_resize: + stacked_images = self.resize( + image=stacked_images, size=size, interpolation=interpolation, antialias=False + ) + resized_images_grouped[shape] = stacked_images + resized_images = reorder_images(resized_images_grouped, grouped_images_index) + + # Group images by size for further processing + # Needed in case do_resize is False, or resize returns images with different sizes + grouped_images, grouped_images_index = group_images_by_shape(resized_images, disable_grouping=disable_grouping) + processed_images_grouped = {} + for shape, stacked_images in grouped_images.items(): + if do_center_crop: + stacked_images = self.center_crop(stacked_images, crop_size) + # Fused rescale and normalize + stacked_images = self.rescale_and_normalize( + stacked_images, do_rescale, rescale_factor, do_normalize, image_mean, image_std + ) + processed_images_grouped[shape] = stacked_images + processed_images = reorder_images(processed_images_grouped, grouped_images_index) + + if do_pad: + processed_images = self.pad(processed_images, pad_size=pad_size, disable_grouping=disable_grouping) + + return BatchFeature(data={"pixel_values": processed_images}, tensor_type=return_tensors) + + def _get_order_seqs(self, order_logits): + """ + Computes the order sequences for a batch of inputs based on logits. + + This function takes in the order logits, calculates order scores using a sigmoid activation, + and determines the order sequences by ranking the votes derived from the scores. + + Args: + order_logits (`torch.FloatTensor` of shape `(batch_size, num_queries, num_queries)`): + Stacked order logits. + + Returns: + torch.Tensor: A tensor of shape `(batch_size, num_queries)`: + Containing the computed order sequences for each input in the batch. Each row represents the ranked order of elements for the corresponding input in the batch. + """ + order_scores = torch.sigmoid(order_logits) + batch_size, sequence_length, _ = order_scores.shape + + order_votes = order_scores.triu(diagonal=1).sum(dim=1) + (1.0 - order_scores.transpose(1, 2)).tril( + diagonal=-1 + ).sum(dim=1) + + order_pointers = torch.argsort(order_votes, dim=1) + order_seq = torch.empty_like(order_pointers) + ranks = torch.arange(sequence_length, device=order_pointers.device, dtype=order_pointers.dtype).expand( + batch_size, -1 + ) + order_seq.scatter_(1, order_pointers, ranks) + + return order_seq + + def extract_custom_vertices(self, polygon, sharp_angle_thresh=45): + poly = np.array(polygon) + n = len(poly) + res = [] + i = 0 + while i < n: + previous_point = poly[(i - 1) % n] + current_point = poly[i] + next_point = poly[(i + 1) % n] + vector_1 = previous_point - current_point + vector_2 = next_point - current_point + cross_product_value = (vector_1[1] * vector_2[0]) - (vector_1[0] * vector_2[1]) + if cross_product_value < 0: + angle_cos = np.clip( + (vector_1 @ vector_2) / (np.linalg.norm(vector_1) * np.linalg.norm(vector_2)), -1.0, 1.0 + ) + angle = np.degrees(np.arccos(angle_cos)) + if abs(angle - sharp_angle_thresh) < 1: + # Calculate the new point based on the direction of two vectors. + dir_vec = vector_1 / np.linalg.norm(vector_1) + vector_2 / np.linalg.norm(vector_2) + dir_vec = dir_vec / np.linalg.norm(dir_vec) + step_size = (np.linalg.norm(vector_1) + np.linalg.norm(vector_2)) / 2 + new_point = current_point + dir_vec * step_size + res.append(tuple(new_point)) + else: + res.append(tuple(current_point)) + i += 1 + return res + + def _mask2polygon(self, mask, epsilon_ratio=0.004): + """ + Postprocess mask by removing small noise. + Args: + mask (ndarray): The input mask of shape [H, W]. + epsilon_ratio (float): The ratio of epsilon. + Returns: + ndarray: The output mask after postprocessing. + """ + contours, _ = cv2.findContours(mask, cv2.RETR_EXTERNAL, cv2.CHAIN_APPROX_SIMPLE) + + if not contours: + return None + + contours = max(contours, key=cv2.contourArea) + epsilon = epsilon_ratio * cv2.arcLength(contours, True) + approx_contours = cv2.approxPolyDP(contours, epsilon, True) + polygon_points = approx_contours.squeeze() + polygon_points = np.atleast_2d(polygon_points) + + polygon_points = self.extract_custom_vertices(polygon_points) + + return polygon_points + + def _extract_polygon_points_by_masks(self, boxes, masks, scale_ratio): + scale_width, scale_height = scale_ratio[0] / 4, scale_ratio[1] / 4 + mask_height, mask_width = masks.shape[1:] + polygon_points = [] + + for i in range(len(boxes)): + x_min, y_min, x_max, y_max = boxes[i].astype(np.int32) + box_w, box_h = x_max - x_min, y_max - y_min + + # default rect + rect = np.array( + [[x_min, y_min], [x_max, y_min], [x_max, y_max], [x_min, y_max]], + dtype=np.float32, + ) + + if box_w <= 0 or box_h <= 0: + polygon_points.append(rect) + continue + + # crop mask + x_coordinates = [int(round((x_min * scale_width).item())), int(round((x_max * scale_width).item()))] + x_start, x_end = np.clip(x_coordinates, 0, mask_width) + y_coordinates = [int(round((y_min * scale_height).item())), int(round((y_max * scale_height).item()))] + y_start, y_end = np.clip(y_coordinates, 0, mask_height) + cropped_mask = masks[i, y_start:y_end, x_start:x_end] + + # resize mask to match box size + resized_mask = cv2.resize(cropped_mask.astype(np.uint8), (box_w, box_h), interpolation=cv2.INTER_NEAREST) + + polygon = self._mask2polygon(resized_mask) + if polygon is not None and len(polygon) < 4: + polygon_points.append(rect) + continue + if polygon is not None and len(polygon) > 0: + polygon = polygon + np.array([x_min, y_min]) + + polygon_points.append(polygon) + + return polygon_points + + def post_process_object_detection( + self, + outputs, + threshold: float = 0.5, + target_sizes: TensorType | list[tuple] | None = None, + ): + """ + Converts the raw output of [`PPDocLayoutV3ForObjectDetection`] into final bounding boxes in (top_left_x, top_left_y, + bottom_right_x, bottom_right_y) format. Only supports PyTorch. + + Args: + outputs ([`DetrObjectDetectionOutput`]): + Raw outputs of the model. + Returns: + `list[Dict]`: A list of dictionaries, each dictionary containing the scores, labels, boxes and polygon_points for an image + in the batch as predicted by the model. + """ + requires_backends(self, ["torch", "cv2"]) + boxes = outputs.pred_boxes + logits = outputs.logits + order_logits = outputs.order_logits + masks = outputs.out_masks + + order_seqs = self._get_order_seqs(order_logits) + + box_centers, box_dims = torch.split(boxes, 2, dim=-1) + top_left_coords = box_centers - 0.5 * box_dims + bottom_right_coords = box_centers + 0.5 * box_dims + boxes = torch.cat([top_left_coords, bottom_right_coords], dim=-1) + + if target_sizes is not None: + if len(logits) != len(target_sizes): + raise ValueError( + "Make sure that you pass in as many target sizes as the batch dimension of the logits" + ) + if isinstance(target_sizes, list): + img_height, img_width = torch.as_tensor(target_sizes).unbind(1) + else: + img_height, img_width = target_sizes.unbind(1) + scale_factor = torch.stack([img_width, img_height, img_width, img_height], dim=1).to(boxes.device) + boxes = boxes * scale_factor[:, None, :] + + num_top_queries = logits.shape[1] + num_classes = logits.shape[2] + + scores = torch.nn.functional.sigmoid(logits) + scores, index = torch.topk(scores.flatten(1), num_top_queries, dim=-1) + labels = index % num_classes + index = index // num_classes + boxes = boxes.gather(dim=1, index=index.unsqueeze(-1).repeat(1, 1, boxes.shape[-1])) + masks = masks.gather( + dim=1, index=index.unsqueeze(-1).unsqueeze(-1).repeat(1, 1, masks.shape[-2], masks.shape[-1]) + ) + masks = (masks.sigmoid() > threshold).int() + order_seqs = order_seqs.gather(dim=1, index=index) + + results = [] + for score, label, box, order_seq, target_size, mask in zip( + scores, labels, boxes, order_seqs, target_sizes, masks + ): + order_seq = order_seq[score >= threshold] + order_seq, indices = torch.sort(order_seq) + polygon_points = self._extract_polygon_points_by_masks( + box[score >= threshold][indices].detach().cpu().numpy(), + mask[score >= threshold][indices].detach().cpu().numpy(), + [self.size["width"] / target_size[1], self.size["height"] / target_size[0]], + ) + results.append( + { + "scores": score[score >= threshold][indices], + "labels": label[score >= threshold][indices], + "boxes": box[score >= threshold][indices], + "polygon_points": polygon_points, + "order_seq": order_seq, + } + ) + + return results + + +class PPDocLayoutV3GlobalPointer(nn.Module): + def __init__(self, config): + super().__init__() + self.head_size = config.global_pointer_head_size + self.dense = nn.Linear(config.d_model, self.head_size * 2) + self.dropout = nn.Dropout(config.gp_dropout_value) + + def forward(self, inputs): + batch_size, sequence_length, _ = inputs.shape + query_key_projection = self.dense(inputs).reshape(batch_size, sequence_length, 2, self.head_size) + query_key_projection = self.dropout(query_key_projection) + queries, keys = torch.unbind(query_key_projection, dim=2) + + logits = (queries @ keys.transpose(-2, -1)) / (self.head_size**0.5) + mask = torch.tril(torch.ones(sequence_length, sequence_length, device=logits.device)).bool() + logits = logits.masked_fill(mask.unsqueeze(0), -1e4) + + return logits + + +class PPDocLayoutV3MultiscaleDeformableAttention(RTDetrMultiscaleDeformableAttention): + pass + + +@auto_docstring +class PPDocLayoutV3PreTrainedModel(RTDetrPreTrainedModel): + @torch.no_grad() + def _init_weights(self, module): + """Initialize the weights""" + if isinstance(module, PPDocLayoutV3MultiscaleDeformableAttention): + init.constant_(module.sampling_offsets.weight, 0.0) + default_dtype = torch.get_default_dtype() + thetas = torch.arange(module.n_heads, dtype=torch.int64).to(default_dtype) * ( + 2.0 * math.pi / module.n_heads + ) + grid_init = torch.stack([thetas.cos(), thetas.sin()], -1) + grid_init = ( + (grid_init / grid_init.abs().max(-1, keepdim=True)[0]) + .view(module.n_heads, 1, 1, 2) + .repeat(1, module.n_levels, module.n_points, 1) + ) + for i in range(module.n_points): + grid_init[:, :, i, :] *= i + 1 + + init.copy_(module.sampling_offsets.bias, grid_init.view(-1)) + init.constant_(module.attention_weights.weight, 0.0) + init.constant_(module.attention_weights.bias, 0.0) + init.xavier_uniform_(module.value_proj.weight) + init.constant_(module.value_proj.bias, 0.0) + init.xavier_uniform_(module.output_proj.weight) + init.constant_(module.output_proj.bias, 0.0) + + elif isinstance(module, PPDocLayoutV3Model): + prior_prob = self.config.initializer_bias_prior_prob or 1 / (self.config.num_labels + 1) + bias = float(-math.log((1 - prior_prob) / prior_prob)) + init.xavier_uniform_(module.enc_score_head.weight) + init.constant_(module.enc_score_head.bias, bias) + init.xavier_uniform_(module.decoder.class_embed.weight) + init.constant_(module.decoder.class_embed.bias, bias) + + elif isinstance(module, (nn.Linear, nn.Conv2d, nn.BatchNorm2d)): + init.normal_(module.weight, mean=0.0, std=self.config.initializer_range) + if module.bias is not None: + init.zeros_(module.bias) + if getattr(module, "running_mean", None) is not None: + init.zeros_(module.running_mean) + init.ones_(module.running_var) + init.zeros_(module.num_batches_tracked) + + elif isinstance(module, nn.LayerNorm): + init.ones_(module.weight) + init.zeros_(module.bias) + + if isinstance(module, nn.Embedding): + init.normal_(module.weight, mean=0.0, std=self.config.initializer_range) + if module.padding_idx is not None: + init.zeros_(module.weight.data[module.padding_idx]) + + +def mask_to_box_coordinate(mask, dtype): + mask = mask.bool() + + height, width = mask.shape[-2:] + + y_coords, x_coords = torch.meshgrid( + torch.arange(height, device=mask.device), torch.arange(width, device=mask.device), indexing="ij" + ) + x_coords = x_coords.to(dtype) + y_coords = y_coords.to(dtype) + + x_coords_masked = x_coords * mask + x_max = x_coords_masked.flatten(start_dim=-2).max(dim=-1).values + 1 + x_min = ( + torch.where(mask, x_coords_masked, torch.tensor(torch.finfo(dtype).max)) + .flatten(start_dim=-2) + .min(dim=-1) + .values + ) + + y_coords_masked = y_coords * mask + y_max = y_coords_masked.flatten(start_dim=-2).max(dim=-1).values + 1 + y_min = ( + torch.where(mask, y_coords_masked, torch.tensor(torch.finfo(dtype).max)) + .flatten(start_dim=-2) + .min(dim=-1) + .values + ) + + unnormalized_bbox = torch.stack([x_min, y_min, x_max, y_max], dim=-1) + + is_mask_non_empty = torch.any(mask, dim=(-2, -1)).unsqueeze(-1) + unnormalized_bbox = unnormalized_bbox * is_mask_non_empty + + norm_tensor = torch.tensor([width, height, width, height], device=mask.device, dtype=dtype) + normalized_bbox_xyxy = unnormalized_bbox / norm_tensor + + x_min_norm, y_min_norm, x_max_norm, y_max_norm = normalized_bbox_xyxy.unbind(dim=-1) + + center_x = (x_min_norm + x_max_norm) / 2 + center_y = (y_min_norm + y_max_norm) / 2 + box_width = x_max_norm - x_min_norm + box_height = y_max_norm - y_min_norm + + return torch.stack([center_x, center_y, box_width, box_height], dim=-1) + + +@dataclass +class PPDocLayoutV3DecoderOutput(RTDetrDecoderOutput): + r""" + intermediate_hidden_states (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, hidden_size)`): + Stacked intermediate hidden states (output of each layer of the decoder). + intermediate_logits (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, sequence_length, config.num_labels)`): + Stacked intermediate logits (logits of each layer of the decoder). + intermediate_reference_points (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, sequence_length, hidden_size)`): + Stacked intermediate reference points (reference points of each layer of the decoder). + intermediate_predicted_corners (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, 4)`): + Stacked intermediate predicted corners (predicted corners of each layer of the decoder). + initial_reference_points (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, 4)`): + Stacked initial reference points (initial reference points of each layer of the decoder). + cross_attentions (`tuple(torch.FloatTensor)`, *optional*, returned when `output_attentions=True` and `config.add_cross_attention=True` is passed or when `config.output_attentions=True`): + Tuple of `torch.FloatTensor` (one for each layer) of shape `(batch_size, num_heads, sequence_length, + sequence_length)`. Attentions weights of the decoder's cross-attention layer, after the attention softmax, + used to compute the weighted average in the cross-attention heads. + decoder_out_order_logits (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, config.num_queries, config.num_queries)`): + Stacked order logits (order logits of each layer of the decoder). + decoder_out_masks (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, config.num_queries, 200, 200)`): + Stacked masks (masks of each layer of the decoder). + """ + + decoder_out_order_logits: torch.FloatTensor | None = None + decoder_out_masks: torch.FloatTensor | None = None + + +@dataclass +@auto_docstring( + custom_intro=""" + Base class for outputs of the PP-DocLayoutV3 model. + """ +) +class PPDocLayoutV3ModelOutput(RTDetrModelOutput): + r""" + last_hidden_state (`torch.FloatTensor` of shape `(batch_size, num_queries, hidden_size)`): + Sequence of hidden-states at the output of the last layer of the decoder of the model. + intermediate_hidden_states (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, hidden_size)`): + Stacked intermediate hidden states (output of each layer of the decoder). + intermediate_logits (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, sequence_length, config.num_labels)`): + Stacked intermediate logits (logits of each layer of the decoder). + intermediate_reference_points (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, 4)`): + Stacked intermediate reference points (reference points of each layer of the decoder). + intermediate_predicted_corners (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, 4)`): + Stacked intermediate predicted corners (predicted corners of each layer of the decoder). + initial_reference_points (`torch.FloatTensor` of shape `(batch_size, num_queries, 4)`): + Initial reference points used for the first decoder layer. + init_reference_points (`torch.FloatTensor` of shape `(batch_size, num_queries, 4)`): + Initial reference points sent through the Transformer decoder. + enc_topk_logits (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.num_labels)`): + Predicted bounding boxes scores where the top `config.two_stage_num_proposals` scoring bounding boxes are + picked as region proposals in the encoder stage. Output of bounding box binary classification (i.e. + foreground and background). + enc_topk_bboxes (`torch.FloatTensor` of shape `(batch_size, sequence_length, 4)`): + Logits of predicted bounding boxes coordinates in the encoder stage. + enc_outputs_class (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.num_labels)`, *optional*, returned when `config.with_box_refine=True` and `config.two_stage=True`): + Predicted bounding boxes scores where the top `config.two_stage_num_proposals` scoring bounding boxes are + picked as region proposals in the first stage. Output of bounding box binary classification (i.e. + foreground and background). + enc_outputs_coord_logits (`torch.FloatTensor` of shape `(batch_size, sequence_length, 4)`, *optional*, returned when `config.with_box_refine=True` and `config.two_stage=True`): + Logits of predicted bounding boxes coordinates in the first stage. + denoising_meta_values (`dict`): + Extra dictionary for the denoising related values. + out_order_logits (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, config.num_queries, config.num_queries)`): + Stacked order logits (order logits of each layer of the decoder). + out_masks (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, config.num_queries, 200, 200)`): + Stacked masks (masks of each layer of the decoder). + """ + + out_order_logits: torch.FloatTensor | None = None + out_masks: torch.FloatTensor | None = None + + +class PPDocLayoutV3MLPPredictionHead(RTDetrMLPPredictionHead): + pass + + +class PPDocLayoutV3ConvLayer(ResNetConvLayer): + pass + + +class PPDocLayoutV3ScaleHead(nn.Module): + def __init__(self, in_channels, feature_channels, fpn_stride, base_stride, align_corners=False): + super().__init__() + head_length = max(1, int(np.log2(fpn_stride) - np.log2(base_stride))) + self.layers = nn.ModuleList() + for k in range(head_length): + in_c = in_channels if k == 0 else feature_channels + self.layers.append(PPDocLayoutV3ConvLayer(in_c, feature_channels, 3, 1, "silu")) + if fpn_stride != base_stride: + self.layers.append(nn.Upsample(scale_factor=2, mode="bilinear", align_corners=align_corners)) + + def forward(self, x): + for layer in self.layers: + x = layer(x) + return x + + +class PPDocLayoutV3MaskFeatFPN(nn.Module): + def __init__( + self, + in_channels=[256, 256, 256], + fpn_strides=[32, 16, 8], + feature_channels=256, + dropout_ratio=0.0, + out_channels=256, + align_corners=False, + ): + super().__init__() + + reorder_index = np.argsort(fpn_strides, axis=0).tolist() + in_channels = [in_channels[i] for i in reorder_index] + fpn_strides = [fpn_strides[i] for i in reorder_index] + + self.reorder_index = reorder_index + self.fpn_strides = fpn_strides + self.dropout_ratio = dropout_ratio + self.align_corners = align_corners + if self.dropout_ratio > 0: + self.dropout = nn.Dropout2d(dropout_ratio) + + self.scale_heads = nn.ModuleList() + for i in range(len(fpn_strides)): + self.scale_heads.append( + PPDocLayoutV3ScaleHead( + in_channels=in_channels[i], + feature_channels=feature_channels, + fpn_stride=fpn_strides[i], + base_stride=fpn_strides[0], + align_corners=align_corners, + ) + ) + self.output_conv = PPDocLayoutV3ConvLayer(feature_channels, out_channels, 3, 1, "silu") + + def forward(self, inputs): + x = [inputs[i] for i in self.reorder_index] + + output = self.scale_heads[0](x[0]) + for i in range(1, len(self.fpn_strides)): + output = output + F.interpolate( + self.scale_heads[i](x[i]), size=output.shape[2:], mode="bilinear", align_corners=self.align_corners + ) + + if self.dropout_ratio > 0: + output = self.dropout(output) + output = self.output_conv(output) + return output + + +class PPDocLayoutV3EncoderMaskOutput(nn.Module): + def __init__(self, in_channels, num_prototypes): + super().__init__() + self.base_conv = PPDocLayoutV3ConvLayer(in_channels, in_channels, 3, 1, "silu") + self.conv = nn.Conv2d(in_channels, num_prototypes, kernel_size=1) + + def forward(self, x): + x = self.base_conv(x) + x = self.conv(x) + return x + + +class PPDocLayoutV3HybridEncoder(RTDetrHybridEncoder): + """ + Main difference to `RTDetrHybridEncoder`: + 1. Mask Feature Head: Added `PPDocLayoutV3MaskFeatFPN` module (`self.mask_feature_head`) for document - specific mask feature generation. + 2. Extra Conv Layers: Introduced `self.encoder_mask_lateral` and `self.encoder_mask_output` for mask feature processing and output. + """ + + def __init__(self, config: PPDocLayoutV3Config): + super().__init__() + + feat_strides = config.feat_strides + mask_feature_channels = config.mask_feature_channels + self.mask_feature_head = PPDocLayoutV3MaskFeatFPN( + [self.encoder_hidden_dim] * len(feat_strides), + feat_strides, + feature_channels=mask_feature_channels[0], + out_channels=mask_feature_channels[1], + ) + self.encoder_mask_lateral = PPDocLayoutV3ConvLayer(config.x4_feat_dim, mask_feature_channels[1], 3, 1, "silu") + self.encoder_mask_output = PPDocLayoutV3EncoderMaskOutput( + in_channels=mask_feature_channels[1], num_prototypes=config.num_prototypes + ) + + def forward( + self, + inputs_embeds=None, + x4_feat=None, + **kwargs: Unpack[TransformersKwargs], + ): + r""" + Args: + inputs_embeds (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`): + Flattened feature map (output of the backbone + projection layer) that is passed to the encoder. + """ + feature_maps = inputs_embeds + + # AIFI: Apply transformer encoder to specified feature levels + if self.config.encoder_layers > 0: + for i, enc_ind in enumerate(self.encode_proj_layers): + feature_maps[enc_ind] = self.aifi[i](feature_maps[enc_ind], **kwargs) + + # top-down FPN + fpn_feature_maps = [feature_maps[-1]] + for idx, (lateral_conv, fpn_block) in enumerate(zip(self.lateral_convs, self.fpn_blocks)): + backbone_feature_map = feature_maps[self.num_fpn_stages - idx - 1] + top_fpn_feature_map = fpn_feature_maps[-1] + # apply lateral block + top_fpn_feature_map = lateral_conv(top_fpn_feature_map) + fpn_feature_maps[-1] = top_fpn_feature_map + # apply fpn block + top_fpn_feature_map = F.interpolate(top_fpn_feature_map, scale_factor=2.0, mode="nearest") + fused_feature_map = torch.concat([top_fpn_feature_map, backbone_feature_map], dim=1) + new_fpn_feature_map = fpn_block(fused_feature_map) + fpn_feature_maps.append(new_fpn_feature_map) + + fpn_feature_maps.reverse() + + # bottom-up PAN + pan_feature_maps = [fpn_feature_maps[0]] + for idx, (downsample_conv, pan_block) in enumerate(zip(self.downsample_convs, self.pan_blocks)): + top_pan_feature_map = pan_feature_maps[-1] + fpn_feature_map = fpn_feature_maps[idx + 1] + downsampled_feature_map = downsample_conv(top_pan_feature_map) + fused_feature_map = torch.concat([downsampled_feature_map, fpn_feature_map], dim=1) + new_pan_feature_map = pan_block(fused_feature_map) + pan_feature_maps.append(new_pan_feature_map) + + mask_feat = self.mask_feature_head(pan_feature_maps) + mask_feat = F.interpolate(mask_feat, scale_factor=2, mode="bilinear", align_corners=False) + mask_feat += self.encoder_mask_lateral(x4_feat[0]) + mask_feat = self.encoder_mask_output(mask_feat) + + return PPDocLayoutV3HybridEncoderOutput( + last_hidden_state=pan_feature_maps, + mask_feat=mask_feat, + ) + + +class PPDocLayoutV3Decoder(RTDetrDecoder): + """ + Main difference to `RTDetrDecoder`: + A new mask generation process is introduced at each decoder layer. + """ + + def __init__(self, config: PPDocLayoutV3Config): + super().__init__() + + self.num_queries = config.num_queries + + def forward( + self, + inputs_embeds=None, + encoder_hidden_states=None, + encoder_attention_mask=None, + reference_points=None, + spatial_shapes=None, + spatial_shapes_list=None, + level_start_index=None, + order_head=None, + global_pointer=None, + mask_query_head=None, + norm=None, + mask_feat=None, + **kwargs: Unpack[TransformersKwargs], + ): + r""" + Args: + inputs_embeds (`torch.FloatTensor` of shape `(batch_size, num_queries, hidden_size)`): + The query embeddings that are passed into the decoder. + encoder_hidden_states (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*): + Sequence of hidden-states at the output of the last layer of the encoder. Used in the cross-attention + of the decoder. + encoder_attention_mask (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Mask to avoid performing cross-attention on padding pixel_values of the encoder. Mask values selected + in `[0, 1]`: + - 1 for pixels that are real (i.e. **not masked**), + - 0 for pixels that are padding (i.e. **masked**). + reference_points (`torch.FloatTensor` of shape `(batch_size, num_queries, 4)` is `as_two_stage` else `(batch_size, num_queries, 2)` or , *optional*): + Reference point in range `[0, 1]`, top-left (0,0), bottom-right (1, 1), including padding area. + spatial_shapes (`torch.FloatTensor` of shape `(num_feature_levels, 2)`): + Spatial shapes of the feature maps. + level_start_index (`torch.LongTensor` of shape `(num_feature_levels)`, *optional*): + Indexes for the start of each feature level. In range `[0, sequence_length]`. + """ + if inputs_embeds is not None: + hidden_states = inputs_embeds + + # decoder layers + intermediate = () + intermediate_reference_points = () + intermediate_logits = () + decoder_out_order_logits = () + decoder_out_masks = () + + reference_points = F.sigmoid(reference_points) + + # https://github.com/lyuwenyu/RT-DETR/blob/94f5e16708329d2f2716426868ec89aa774af016/rtdetr_pytorch/src/zoo/rtdetr/rtdetr_decoder.py#L252 + for idx, decoder_layer in enumerate(self.layers): + reference_points_input = reference_points.unsqueeze(2) + object_queries_position_embeddings = self.query_pos_head(reference_points) + + hidden_states = decoder_layer( + hidden_states, + object_queries_position_embeddings=object_queries_position_embeddings, + encoder_hidden_states=encoder_hidden_states, + reference_points=reference_points_input, + spatial_shapes=spatial_shapes, + spatial_shapes_list=spatial_shapes_list, + level_start_index=level_start_index, + encoder_attention_mask=encoder_attention_mask, + **kwargs, + ) + + # hack implementation for iterative bounding box refinement + if self.bbox_embed is not None: + predicted_corners = self.bbox_embed(hidden_states) + new_reference_points = F.sigmoid(predicted_corners + inverse_sigmoid(reference_points)) + reference_points = new_reference_points.detach() + + intermediate += (hidden_states,) + intermediate_reference_points += ( + (new_reference_points,) if self.bbox_embed is not None else (reference_points,) + ) + + # get_pred_class_order_and_mask + out_query = norm(hidden_states) + mask_query_embed = mask_query_head(out_query) + batch_size, mask_dim, _ = mask_query_embed.shape + _, _, mask_h, mask_w = mask_feat.shape + out_mask = torch.bmm(mask_query_embed, mask_feat.flatten(start_dim=2)).reshape( + batch_size, mask_dim, mask_h, mask_w + ) + decoder_out_masks += (out_mask,) + + if self.class_embed is not None: + logits = self.class_embed(out_query) + intermediate_logits += (logits,) + + if order_head is not None and global_pointer is not None: + valid_query = out_query[:, -self.num_queries :] if self.num_queries is not None else out_query + order_logits = global_pointer(order_head[idx](valid_query)) + decoder_out_order_logits += (order_logits,) + + # Keep batch_size as first dimension + intermediate = torch.stack(intermediate, dim=1) + intermediate_reference_points = torch.stack(intermediate_reference_points, dim=1) + if self.class_embed is not None: + intermediate_logits = torch.stack(intermediate_logits, dim=1) + if order_head is not None and global_pointer is not None: + decoder_out_order_logits = torch.stack(decoder_out_order_logits, dim=1) + decoder_out_masks = torch.stack(decoder_out_masks, dim=1) + + return PPDocLayoutV3DecoderOutput( + last_hidden_state=hidden_states, + intermediate_hidden_states=intermediate, + intermediate_logits=intermediate_logits, + intermediate_reference_points=intermediate_reference_points, + decoder_out_order_logits=decoder_out_order_logits, + decoder_out_masks=decoder_out_masks, + ) + + +@auto_docstring( + custom_intro=""" + PP-DocLayoutV3 Model (consisting of a backbone and encoder-decoder) outputting raw hidden states without any head on top. + """ +) +class PPDocLayoutV3Model(RTDetrModel): + _tied_weights_keys = { + "decoder.class_embed": "enc_score_head", + "decoder.bbox_embed": "enc_bbox_head", + } + + def __init__(self, config: PPDocLayoutV3Config): + super().__init__(config) + + encoder_input_proj_list = [] + self.encoder_input_proj = nn.ModuleList(encoder_input_proj_list[1:]) + + self.decoder_order_head = nn.ModuleList( + [nn.Linear(config.d_model, config.d_model) for _ in range(config.decoder_layers)] + ) + self.decoder_global_pointer = PPDocLayoutV3GlobalPointer(config) + self.decoder_norm = nn.LayerNorm(config.d_model, eps=config.layer_norm_eps) + self.decoder = PPDocLayoutV3Decoder(config) + self.decoder.class_embed = nn.Linear(config.d_model, config.num_labels) + self.decoder.bbox_embed = PPDocLayoutV3MLPPredictionHead(config.d_model, config.d_model, 4, num_layers=3) + + self.mask_enhanced = config.mask_enhanced + self.mask_query_head = PPDocLayoutV3MLPPredictionHead( + config.d_model, config.d_model, config.num_prototypes, num_layers=3 + ) + + @auto_docstring + @can_return_tuple + def forward( + self, + pixel_values: torch.FloatTensor, + pixel_mask: torch.LongTensor | None = None, + encoder_outputs: torch.FloatTensor | None = None, + labels: list[dict] | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.FloatTensor] | PPDocLayoutV3ModelOutput: + r""" + inputs_embeds (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*): + Optionally, instead of passing the flattened feature map (output of the backbone + projection layer), you + can choose to directly pass a flattened representation of an image. + decoder_inputs_embeds (`torch.FloatTensor` of shape `(batch_size, num_queries, hidden_size)`, *optional*): + Optionally, instead of initializing the queries with a tensor of zeros, you can choose to directly pass an + embedded representation. + labels (`list[Dict]` of len `(batch_size,)`, *optional*): + Labels for computing the bipartite matching loss. List of dicts, each dictionary containing at least the + following 2 keys: 'class_labels' and 'boxes' (the class labels and bounding boxes of an image in the batch + respectively). The class labels themselves should be a `torch.LongTensor` of len `(number of bounding boxes + in the image,)` and the boxes a `torch.FloatTensor` of shape `(number of bounding boxes in the image, 4)`. + + Examples: + + ```python + >>> from transformers import AutoImageProcessor, PPDocLayoutV2Model + >>> from PIL import Image + >>> import requests + + >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg" + >>> image = Image.open(requests.get(url, stream=True).raw) + + >>> image_processor = AutoImageProcessor.from_pretrained("PekingU/PPDocLayoutV2_r50vd") + >>> model = PPDocLayoutV2Model.from_pretrained("PekingU/PPDocLayoutV2_r50vd") + + >>> inputs = image_processor(images=image, return_tensors="pt") + + >>> outputs = model(**inputs) + + >>> last_hidden_states = outputs.last_hidden_state + >>> list(last_hidden_states.shape) + [1, 300, 256] + ```""" + batch_size, num_channels, height, width = pixel_values.shape + device = pixel_values.device + + if pixel_mask is None: + pixel_mask = torch.ones(((batch_size, height, width)), device=device) + + features = self.backbone(pixel_values, pixel_mask) + x4_feat = features.pop(0) + proj_feats = [self.encoder_input_proj[level](source) for level, (source, mask) in enumerate(features)] + + if encoder_outputs is None: + encoder_outputs = self.encoder( + proj_feats, + x4_feat, + **kwargs, + ) + # If the user passed a tuple for encoder_outputs, we wrap it in a PPDocLayoutV3HybridEncoderOutput when return_dict=True + elif not isinstance(encoder_outputs, PPDocLayoutV3HybridEncoderOutput): + encoder_outputs = PPDocLayoutV3HybridEncoderOutput( + last_hidden_state=encoder_outputs[0], + hidden_states=encoder_outputs[1] if len(encoder_outputs) > 1 else None, + attentions=encoder_outputs[2] if len(encoder_outputs) > 2 else None, + mask_feat=encoder_outputs[-1], + ) + + # Equivalent to def _get_encoder_input + # https://github.com/lyuwenyu/RT-DETR/blob/94f5e16708329d2f2716426868ec89aa774af016/rtdetr_pytorch/src/zoo/rtdetr/rtdetr_decoder.py#L412 + sources = [] + for level, source in enumerate(encoder_outputs.last_hidden_state): + sources.append(self.decoder_input_proj[level](source)) + + # Lowest resolution feature maps are obtained via 3x3 stride 2 convolutions on the final stage + if self.config.num_feature_levels > len(sources): + _len_sources = len(sources) + sources.append(self.decoder_input_proj[_len_sources](encoder_outputs.last_hidden_state[-1])) + for i in range(_len_sources + 1, self.config.num_feature_levels): + sources.append(self.decoder_input_proj[i](encoder_outputs.last_hidden_state[-1])) + + # Prepare encoder inputs (by flattening) + source_flatten = [] + spatial_shapes_list = [] + spatial_shapes = torch.empty((len(sources), 2), device=device, dtype=torch.long) + for level, source in enumerate(sources): + height, width = source.shape[-2:] + spatial_shapes[level, 0] = height + spatial_shapes[level, 1] = width + spatial_shapes_list.append((height, width)) + source = source.flatten(2).transpose(1, 2) + source_flatten.append(source) + source_flatten = torch.cat(source_flatten, 1) + level_start_index = torch.cat((spatial_shapes.new_zeros((1,)), spatial_shapes.prod(1).cumsum(0)[:-1])) + + # prepare denoising training + if self.training and self.config.num_denoising > 0 and labels is not None: + ( + denoising_class, + denoising_bbox_unact, + attention_mask, + denoising_meta_values, + ) = get_contrastive_denoising_training_group( + targets=labels, + num_classes=self.config.num_labels, + num_queries=self.config.num_queries, + class_embed=self.denoising_class_embed, + num_denoising_queries=self.config.num_denoising, + label_noise_ratio=self.config.label_noise_ratio, + box_noise_scale=self.config.box_noise_scale, + ) + else: + denoising_class, denoising_bbox_unact, attention_mask, denoising_meta_values = None, None, None, None + + batch_size = len(source_flatten) + device = source_flatten.device + dtype = source_flatten.dtype + + # prepare input for decoder + if self.training or self.config.anchor_image_size is None: + # Pass spatial_shapes as tuple to make it hashable and make sure + # lru_cache is working for generate_anchors() + spatial_shapes_tuple = tuple(spatial_shapes_list) + anchors, valid_mask = self.generate_anchors(spatial_shapes_tuple, device=device, dtype=dtype) + else: + anchors, valid_mask = self.anchors, self.valid_mask + anchors, valid_mask = anchors.to(device, dtype), valid_mask.to(device, dtype) + + # use the valid_mask to selectively retain values in the feature map where the mask is `True` + memory = valid_mask.to(source_flatten.dtype) * source_flatten + + output_memory = self.enc_output(memory) + + enc_outputs_class = self.enc_score_head(output_memory) + enc_outputs_coord_logits = self.enc_bbox_head(output_memory) + anchors + + _, topk_ind = torch.topk(enc_outputs_class.max(-1).values, self.config.num_queries, dim=1) + + reference_points_unact = enc_outputs_coord_logits.gather( + dim=1, index=topk_ind.unsqueeze(-1).repeat(1, 1, enc_outputs_coord_logits.shape[-1]) + ) + + # _get_pred_class_and_mask + batch_ind = torch.arange(memory.shape[0], device=output_memory.device).unsqueeze(1) + target = output_memory[batch_ind, topk_ind] + out_query = self.decoder_norm(target) + mask_query_embed = self.mask_query_head(out_query) + batch_size, mask_dim, _ = mask_query_embed.shape + + enc_topk_bboxes = F.sigmoid(reference_points_unact) + + enc_topk_logits = enc_outputs_class.gather( + dim=1, index=topk_ind.unsqueeze(-1).repeat(1, 1, enc_outputs_class.shape[-1]) + ) + + # extract region features + if self.config.learn_initial_query: + target = self.weight_embedding.tile([batch_size, 1, 1]) + else: + target = output_memory.gather(dim=1, index=topk_ind.unsqueeze(-1).repeat(1, 1, output_memory.shape[-1])) + target = target.detach() + + if denoising_class is not None: + target = torch.concat([denoising_class, target], 1) + + if self.mask_enhanced: + _, _, mask_h, mask_w = encoder_outputs.mask_feat.shape + enc_out_masks = torch.bmm(mask_query_embed, encoder_outputs.mask_feat.flatten(start_dim=2)).reshape( + batch_size, mask_dim, mask_h, mask_w + ) + reference_points = mask_to_box_coordinate(enc_out_masks > 0, dtype=reference_points_unact.dtype) + reference_points_unact = inverse_sigmoid(reference_points) + + if denoising_bbox_unact is not None: + reference_points_unact = torch.concat([denoising_bbox_unact, reference_points_unact], 1) + + init_reference_points = reference_points_unact.detach() + + # decoder + decoder_outputs = self.decoder( + inputs_embeds=target, + encoder_hidden_states=source_flatten, + encoder_attention_mask=attention_mask, + reference_points=init_reference_points, + spatial_shapes=spatial_shapes, + spatial_shapes_list=spatial_shapes_list, + level_start_index=level_start_index, + order_head=self.decoder_order_head, + global_pointer=self.decoder_global_pointer, + mask_query_head=self.mask_query_head, + norm=self.decoder_norm, + mask_feat=encoder_outputs.mask_feat, + **kwargs, + ) + + return PPDocLayoutV3ModelOutput( + last_hidden_state=decoder_outputs.last_hidden_state, + intermediate_hidden_states=decoder_outputs.intermediate_hidden_states, + intermediate_logits=decoder_outputs.intermediate_logits, + intermediate_reference_points=decoder_outputs.intermediate_reference_points, + intermediate_predicted_corners=decoder_outputs.intermediate_predicted_corners, + initial_reference_points=decoder_outputs.initial_reference_points, + decoder_hidden_states=decoder_outputs.hidden_states, + decoder_attentions=decoder_outputs.attentions, + cross_attentions=decoder_outputs.cross_attentions, + out_order_logits=decoder_outputs.decoder_out_order_logits, + out_masks=decoder_outputs.decoder_out_masks, + encoder_last_hidden_state=encoder_outputs.last_hidden_state, + encoder_hidden_states=encoder_outputs.hidden_states, + encoder_attentions=encoder_outputs.attentions, + init_reference_points=init_reference_points, + enc_topk_logits=enc_topk_logits, + enc_topk_bboxes=enc_topk_bboxes, + enc_outputs_class=enc_outputs_class, + enc_outputs_coord_logits=enc_outputs_coord_logits, + denoising_meta_values=denoising_meta_values, + ) + + +@dataclass +@auto_docstring +class PPDocLayoutV3HybridEncoderOutput(BaseModelOutput): + r""" + mask_feat (`torch.FloatTensor` of shape `(batch_size, config.num_queries, 200, 200)`): + Mask features for each query in the batch. + """ + + mask_feat: torch.FloatTensor = None + + +@dataclass +@auto_docstring +class PPDocLayoutV3ForObjectDetectionOutput(ModelOutput): + r""" + logits (`torch.FloatTensor` of shape `(batch_size, num_queries, num_classes + 1)`): + Classification logits (including no-object) for all queries. + pred_boxes (`torch.FloatTensor` of shape `(batch_size, num_queries, 4)`): + Normalized boxes coordinates for all queries, represented as (center_x, center_y, width, height). These + values are normalized in [0, 1], relative to the size of each individual image in the batch (disregarding + possible padding). You can use [`~PPDocLayoutV3ImageProcessorFast.post_process_object_detection`] to retrieve the + unnormalized (absolute) bounding boxes. + order_logits (`tuple` of `torch.FloatTensor` of shape `(batch_size, num_queries, num_queries)`): + Order logits of the final layer of the decoder. + out_masks (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, height, width)`): + Masks of the final layer of the decoder. + last_hidden_state (`torch.FloatTensor` of shape `(batch_size, num_queries, hidden_size)`): + Sequence of hidden-states at the output of the last layer of the decoder of the model. + intermediate_hidden_states (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, hidden_size)`): + Stacked intermediate hidden states (output of each layer of the decoder). + intermediate_logits (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, config.num_labels)`): + Stacked intermediate logits (logits of each layer of the decoder). + intermediate_reference_points (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, 4)`): + Stacked intermediate reference points (reference points of each layer of the decoder). + intermediate_predicted_corners (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, 4)`): + Stacked intermediate predicted corners (predicted corners of each layer of the decoder). + initial_reference_points (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, 4)`): + Stacked initial reference points (initial reference points of each layer of the decoder). + init_reference_points (`torch.FloatTensor` of shape `(batch_size, num_queries, 4)`): + Initial reference points sent through the Transformer decoder. + enc_topk_logits (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.num_labels)`, *optional*, returned when `config.with_box_refine=True` and `config.two_stage=True`): + Logits of predicted bounding boxes coordinates in the encoder. + enc_topk_bboxes (`torch.FloatTensor` of shape `(batch_size, sequence_length, 4)`, *optional*, returned when `config.with_box_refine=True` and `config.two_stage=True`): + Logits of predicted bounding boxes coordinates in the encoder. + enc_outputs_class (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.num_labels)`, *optional*, returned when `config.with_box_refine=True` and `config.two_stage=True`): + Predicted bounding boxes scores where the top `config.two_stage_num_proposals` scoring bounding boxes are + picked as region proposals in the first stage. Output of bounding box binary classification (i.e. + foreground and background). + enc_outputs_coord_logits (`torch.FloatTensor` of shape `(batch_size, sequence_length, 4)`, *optional*, returned when `config.with_box_refine=True` and `config.two_stage=True`): + Logits of predicted bounding boxes coordinates in the first stage. + denoising_meta_values (`dict`): + Extra dictionary for the denoising related values + """ + + logits: torch.FloatTensor | None = None + pred_boxes: torch.FloatTensor | None = None + order_logits: torch.FloatTensor | None = None + out_masks: torch.FloatTensor | None = None + last_hidden_state: torch.FloatTensor | None = None + intermediate_hidden_states: torch.FloatTensor | None = None + intermediate_logits: torch.FloatTensor | None = None + intermediate_reference_points: torch.FloatTensor | None = None + intermediate_predicted_corners: torch.FloatTensor | None = None + initial_reference_points: torch.FloatTensor | None = None + decoder_hidden_states: tuple[torch.FloatTensor] | None = None + decoder_attentions: tuple[torch.FloatTensor] | None = None + cross_attentions: tuple[torch.FloatTensor] | None = None + encoder_last_hidden_state: torch.FloatTensor | None = None + encoder_hidden_states: tuple[torch.FloatTensor] | None = None + encoder_attentions: tuple[torch.FloatTensor] | None = None + init_reference_points: tuple[torch.FloatTensor] | None = None + enc_topk_logits: torch.FloatTensor | None = None + enc_topk_bboxes: torch.FloatTensor | None = None + enc_outputs_class: torch.FloatTensor | None = None + enc_outputs_coord_logits: torch.FloatTensor | None = None + denoising_meta_values: dict | None = None + + +@auto_docstring( + custom_intro=""" + PP-DocLayoutV3 Model (consisting of a backbone and encoder-decoder) outputs bounding boxes and logits sorted according to reading order, + which are further decoded into scores and classes. + """ +) +class PPDocLayoutV3ForObjectDetection(RTDetrForObjectDetection, PPDocLayoutV3PreTrainedModel): + _keys_to_ignore_on_load_missing = ["num_batches_tracked", "rel_pos_y_bias", "rel_pos_x_bias"] + + def __init__(self, config: PPDocLayoutV3Config): + super().__init__(config) + + del self.model.decoder.class_embed + del self.model.decoder.bbox_embed + del num_pred # noqa + + self.model.denoising_class_embed = nn.Embedding(config.num_labels, config.d_model) + self.num_queries = config.num_queries + + self.post_init() + + @auto_docstring + @can_return_tuple + def forward( + self, + pixel_values: torch.FloatTensor, + pixel_mask: torch.LongTensor | None = None, + encoder_outputs: torch.FloatTensor | None = None, + labels: list[dict] | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.FloatTensor] | PPDocLayoutV3ForObjectDetectionOutput: + r""" + inputs_embeds (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*): + Optionally, instead of passing the flattened feature map (output of the backbone + projection layer), you + can choose to directly pass a flattened representation of an image. + decoder_inputs_embeds (`torch.FloatTensor` of shape `(batch_size, num_queries, hidden_size)`, *optional*): + Optionally, instead of initializing the queries with a tensor of zeros, you can choose to directly pass an + embedded representation. + labels (`list[Dict]` of len `(batch_size,)`, *optional*): + Labels for computing the bipartite matching loss. List of dicts, each dictionary containing at least the + following 2 keys: 'class_labels' and 'boxes' (the class labels and bounding boxes of an image in the batch + respectively). The class labels themselves should be a `torch.LongTensor` of len `(number of bounding boxes + in the image,)` and the boxes a `torch.FloatTensor` of shape `(number of bounding boxes in the image, 4)`. + + Examples: + + ```python + >>> from transformers import AutoModelForObjectDetection, AutoImageProcessor + >>> from PIL import Image + >>> import requests + >>> import torch + + >>> url = "https://paddle-model-ecology.bj.bcebos.com/paddlex/imgs/demo_image/layout_demo.jpg" + >>> image = Image.open(requests.get(url, stream=True).raw) + + >>> model_path = "PaddlePaddle/PP-DocLayoutV3_safetensors" + >>> image_processor = AutoImageProcessor.from_pretrained(model_path) + >>> model = AutoModelForObjectDetection.from_pretrained(model_path) + + >>> # prepare image for the model + >>> inputs = image_processor(images=[image], return_tensors="pt") + + >>> # forward pass + >>> outputs = model(**inputs) + + >>> # convert outputs (bounding boxes and class logits) to Pascal VOC format (xmin, ymin, xmax, ymax) + >>> results = image_processor.post_process_object_detection(outputs, target_sizes=torch.tensor([image.size[::-1]])) + + >>> # print outputs + >>> for result in results: + ... for idx, (score, label_id, box) in enumerate(zip(result["scores"], result["labels"], result["boxes"])): + ... score, label = score.item(), label_id.item() + ... box = [round(i, 2) for i in box.tolist()] + ... print(f"Order {idx + 1}: {model.config.id2label[label]}: {score:.2f} {box}") + Order 1: text: 0.99 [334.95, 184.78, 897.25, 654.83] + Order 2: paragraph_title: 0.97 [337.28, 683.92, 869.16, 798.35] + Order 3: text: 0.99 [335.75, 842.82, 892.13, 1454.32] + Order 4: text: 0.99 [920.18, 185.28, 1476.38, 464.49] + Order 5: text: 0.98 [920.47, 483.68, 1480.63, 765.72] + Order 6: text: 0.98 [920.62, 846.8, 1482.09, 1220.67] + Order 7: text: 0.97 [920.92, 1239.41, 1469.55, 1378.02] + Order 8: footnote: 0.86 [335.03, 1614.68, 1483.33, 1731.73] + Order 9: footnote: 0.83 [334.64, 1756.74, 1471.78, 1845.69] + Order 10: text: 0.81 [336.8, 1910.52, 661.64, 1939.92] + Order 11: footnote: 0.96 [336.24, 2114.42, 1450.14, 2172.12] + Order 12: number: 0.88 [106.0, 2257.5, 135.84, 2282.18] + Order 13: footer: 0.93 [338.4, 2255.52, 986.15, 2284.37] + ```""" + outputs = self.model( + pixel_values, + pixel_mask=pixel_mask, + encoder_outputs=encoder_outputs, + labels=labels, + **kwargs, + ) + + intermediate_logits = outputs.intermediate_logits + intermediate_reference_points = outputs.intermediate_reference_points + order_logits = outputs.out_order_logits + out_masks = outputs.out_masks + + pred_boxes = intermediate_reference_points[:, -1] + logits = intermediate_logits[:, -1] + order_logits = order_logits[:, -1] + out_masks = out_masks[:, -1] + + if labels is not None: + raise ValueError("PPDocLayoutV3ForObjectDetection does not support training") + + return PPDocLayoutV3ForObjectDetectionOutput( + logits=logits, + pred_boxes=pred_boxes, + order_logits=order_logits, + out_masks=out_masks, + last_hidden_state=outputs.last_hidden_state, + intermediate_hidden_states=outputs.intermediate_hidden_states, + intermediate_logits=outputs.intermediate_logits, + intermediate_reference_points=outputs.intermediate_reference_points, + intermediate_predicted_corners=outputs.intermediate_predicted_corners, + initial_reference_points=outputs.initial_reference_points, + decoder_hidden_states=outputs.decoder_hidden_states, + decoder_attentions=outputs.decoder_attentions, + cross_attentions=outputs.cross_attentions, + encoder_last_hidden_state=outputs.encoder_last_hidden_state, + encoder_hidden_states=outputs.encoder_hidden_states, + encoder_attentions=outputs.encoder_attentions, + init_reference_points=outputs.init_reference_points, + enc_topk_logits=outputs.enc_topk_logits, + enc_topk_bboxes=outputs.enc_topk_bboxes, + enc_outputs_class=outputs.enc_outputs_class, + enc_outputs_coord_logits=outputs.enc_outputs_coord_logits, + denoising_meta_values=outputs.denoising_meta_values, + ) + + +__all__ = [ + "PPDocLayoutV3ForObjectDetection", + "PPDocLayoutV3ImageProcessorFast", + "PPDocLayoutV3Config", + "PPDocLayoutV3Model", + "PPDocLayoutV3PreTrainedModel", +] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/prompt_depth_anything/__init__.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/prompt_depth_anything/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..0f2206150f0ac1d5aba781c2aee6654dd03023fe --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/prompt_depth_anything/__init__.py @@ -0,0 +1,32 @@ +# Copyright 2024 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from typing import TYPE_CHECKING + +from ...utils import _LazyModule +from ...utils.import_utils import define_import_structure + + +if TYPE_CHECKING: + from .configuration_prompt_depth_anything import PromptDepthAnythingConfig + from .image_processing_prompt_depth_anything import PromptDepthAnythingImageProcessor + from .image_processing_prompt_depth_anything_fast import PromptDepthAnythingImageProcessorFast + from .modeling_prompt_depth_anything import ( + PromptDepthAnythingForDepthEstimation, + PromptDepthAnythingPreTrainedModel, + ) +else: + import sys + + _file = globals()["__file__"] + sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__) diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/prompt_depth_anything/configuration_prompt_depth_anything.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/prompt_depth_anything/configuration_prompt_depth_anything.py new file mode 100644 index 0000000000000000000000000000000000000000..ffa4e3086f343f3fad9a8c90a5bec81bec8b2cd6 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/prompt_depth_anything/configuration_prompt_depth_anything.py @@ -0,0 +1,124 @@ +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# This file was automatically generated from src/transformers/models/prompt_depth_anything/modular_prompt_depth_anything.py. +# Do NOT edit this file manually as any edits will be overwritten by the generation of +# the file from the modular. If any change should be done, please apply the change to the +# modular_prompt_depth_anything.py file directly. One of our CI enforces this. +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# Copyright 2025 The HuggingFace Team. All rights reserved. +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + + +from ...backbone_utils import consolidate_backbone_kwargs_to_config +from ...configuration_utils import PreTrainedConfig +from ..auto.configuration_auto import AutoConfig + + +class PromptDepthAnythingConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`PromptDepthAnythingModel`]. It is used to instantiate a PromptDepthAnything + model according to the specified arguments, defining the model architecture. Instantiating a configuration with the + defaults will yield a similar configuration to that of the PromptDepthAnything + [LiheYoung/depth-anything-small-hf](https://huggingface.co/LiheYoung/depth-anything-small-hf) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + backbone_config (`Union[dict, "PreTrainedConfig"]`, *optional*, defaults to `Dinov2Config()`): + The configuration of the backbone model. + patch_size (`int`, *optional*, defaults to 14): + The size of the patches to extract from the backbone features. + initializer_range (`float`, *optional*, defaults to 0.02): + The standard deviation of the truncated_normal_initializer for initializing all weight matrices. + reassemble_hidden_size (`int`, *optional*, defaults to 384): + The number of input channels of the reassemble layers. + reassemble_factors (`list[int]`, *optional*, defaults to `[4, 2, 1, 0.5]`): + The up/downsampling factors of the reassemble layers. + neck_hidden_sizes (`list[str]`, *optional*, defaults to `[48, 96, 192, 384]`): + The hidden sizes to project to for the feature maps of the backbone. + fusion_hidden_size (`int`, *optional*, defaults to 64): + The number of channels before fusion. + head_in_index (`int`, *optional*, defaults to -1): + The index of the features to use in the depth estimation head. + head_hidden_size (`int`, *optional*, defaults to 32): + The number of output channels in the second convolution of the depth estimation head. + depth_estimation_type (`str`, *optional*, defaults to `"relative"`): + The type of depth estimation to use. Can be one of `["relative", "metric"]`. + max_depth (`float`, *optional*): + The maximum depth to use for the "metric" depth estimation head. 20 should be used for indoor models + and 80 for outdoor models. For "relative" depth estimation, this value is ignored. + + Example: + + ```python + >>> from transformers import PromptDepthAnythingConfig, PromptDepthAnythingForDepthEstimation + + >>> # Initializing a PromptDepthAnything small style configuration + >>> configuration = PromptDepthAnythingConfig() + + >>> # Initializing a model from the PromptDepthAnything small style configuration + >>> model = PromptDepthAnythingForDepthEstimation(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "prompt_depth_anything" + sub_configs = {"backbone_config": AutoConfig} + + def __init__( + self, + backbone_config=None, + patch_size=14, + initializer_range=0.02, + reassemble_hidden_size=384, + reassemble_factors=[4, 2, 1, 0.5], + neck_hidden_sizes=[48, 96, 192, 384], + fusion_hidden_size=64, + head_in_index=-1, + head_hidden_size=32, + depth_estimation_type="relative", + max_depth=None, + **kwargs, + ): + backbone_config, kwargs = consolidate_backbone_kwargs_to_config( + backbone_config=backbone_config, + default_config_type="dinov2", + default_config_kwargs={ + "image_size": 518, + "hidden_size": 384, + "num_attention_heads": 6, + "out_indices": [9, 10, 11, 12], + "reshape_hidden_states": False, + }, + **kwargs, + ) + + self.backbone_config = backbone_config + self.reassemble_hidden_size = reassemble_hidden_size + self.patch_size = patch_size + self.initializer_range = initializer_range + self.reassemble_factors = reassemble_factors + self.neck_hidden_sizes = neck_hidden_sizes + self.fusion_hidden_size = fusion_hidden_size + self.head_in_index = head_in_index + self.head_hidden_size = head_hidden_size + if depth_estimation_type not in ["relative", "metric"]: + raise ValueError("depth_estimation_type must be one of ['relative', 'metric']") + self.depth_estimation_type = depth_estimation_type + self.max_depth = max_depth if max_depth else 1 + + super().__init__(**kwargs) + + +__all__ = ["PromptDepthAnythingConfig"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/prompt_depth_anything/image_processing_prompt_depth_anything.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/prompt_depth_anything/image_processing_prompt_depth_anything.py new file mode 100644 index 0000000000000000000000000000000000000000..369afaf46998abde4b386119d5fd4e16a5d2f9c0 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/prompt_depth_anything/image_processing_prompt_depth_anything.py @@ -0,0 +1,514 @@ +# Copyright 2024 The HuggingFace Team. All rights reserved. +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""Image processor class for PromptDepthAnything.""" + +import math +from typing import TYPE_CHECKING + + +if TYPE_CHECKING: + from ...modeling_outputs import DepthEstimatorOutput + +import numpy as np + +from ...image_processing_utils import BaseImageProcessor, BatchFeature, get_size_dict +from ...image_transforms import pad, resize, to_channel_dimension_format +from ...image_utils import ( + IMAGENET_STANDARD_MEAN, + IMAGENET_STANDARD_STD, + ChannelDimension, + ImageInput, + PILImageResampling, + get_image_size, + infer_channel_dimension_format, + is_scaled_image, + is_torch_available, + make_flat_list_of_images, + to_numpy_array, + valid_images, + validate_preprocess_arguments, +) +from ...processing_utils import ImagesKwargs +from ...utils import ( + TensorType, + filter_out_non_signature_kwargs, + logging, + requires_backends, +) + + +if is_torch_available(): + import torch + + +logger = logging.get_logger(__name__) + + +class PromptDepthAnythingImageProcessorKwargs(ImagesKwargs, total=False): + r""" + keep_aspect_ratio (`bool`, *optional*): + If `True`, the image is resized to the largest possible size such that the aspect ratio is preserved. + ensure_multiple_of (`int`, *optional*): + If `do_resize` is `True`, the image is resized to a size that is a multiple of this value. + prompt_scale_to_meter (`float`, *optional*): + Scale factor to convert the prompt depth to meters. + """ + + keep_aspect_ratio: bool + ensure_multiple_of: int + size_divisor: int + prompt_scale_to_meter: float + + +def _constrain_to_multiple_of(val, multiple, min_val=0, max_val=None): + x = round(val / multiple) * multiple + + if max_val is not None and x > max_val: + x = math.floor(val / multiple) * multiple + + if x < min_val: + x = math.ceil(val / multiple) * multiple + + return x + + +def _get_resize_output_image_size( + input_image: np.ndarray, + output_size: tuple[int, int], + keep_aspect_ratio: bool, + multiple: int, + input_data_format: str | ChannelDimension | None = None, +) -> tuple[int, int]: + input_height, input_width = get_image_size(input_image, input_data_format) + output_height, output_width = output_size + + # determine new height and width + scale_height = output_height / input_height + scale_width = output_width / input_width + + if keep_aspect_ratio: + # scale as little as possible + if abs(1 - scale_width) < abs(1 - scale_height): + # fit width + scale_height = scale_width + else: + # fit height + scale_width = scale_height + + new_height = _constrain_to_multiple_of(scale_height * input_height, multiple=multiple) + new_width = _constrain_to_multiple_of(scale_width * input_width, multiple=multiple) + + return (new_height, new_width) + + +class PromptDepthAnythingImageProcessor(BaseImageProcessor): + r""" + Constructs a PromptDepthAnything image processor. + + Args: + do_resize (`bool`, *optional*, defaults to `True`): + Whether to resize the image's (height, width) dimensions. Can be overridden by `do_resize` in `preprocess`. + size (`dict[str, int]` *optional*, defaults to `{"height": 384, "width": 384}`): + Size of the image after resizing. Can be overridden by `size` in `preprocess`. + resample (`PILImageResampling`, *optional*, defaults to `Resampling.BICUBIC`): + Defines the resampling filter to use if resizing the image. Can be overridden by `resample` in `preprocess`. + keep_aspect_ratio (`bool`, *optional*, defaults to `False`): + If `True`, the image is resized to the largest possible size such that the aspect ratio is preserved. Can + be overridden by `keep_aspect_ratio` in `preprocess`. + ensure_multiple_of (`int`, *optional*, defaults to 1): + If `do_resize` is `True`, the image is resized to a size that is a multiple of this value. Can be overridden + by `ensure_multiple_of` in `preprocess`. + do_rescale (`bool`, *optional*, defaults to `True`): + Whether to rescale the image by the specified scale `rescale_factor`. Can be overridden by `do_rescale` in + `preprocess`. + rescale_factor (`int` or `float`, *optional*, defaults to `1/255`): + Scale factor to use if rescaling the image. Can be overridden by `rescale_factor` in `preprocess`. + do_normalize (`bool`, *optional*, defaults to `True`): + Whether to normalize the image. Can be overridden by the `do_normalize` parameter in the `preprocess` + method. + image_mean (`float` or `list[float]`, *optional*, defaults to `IMAGENET_STANDARD_MEAN`): + Mean to use if normalizing the image. This is a float or list of floats the length of the number of + channels in the image. Can be overridden by the `image_mean` parameter in the `preprocess` method. + image_std (`float` or `list[float]`, *optional*, defaults to `IMAGENET_STANDARD_STD`): + Standard deviation to use if normalizing the image. This is a float or list of floats the length of the + number of channels in the image. Can be overridden by the `image_std` parameter in the `preprocess` method. + do_pad (`bool`, *optional*, defaults to `False`): + Whether to apply center padding. This was introduced in the DINOv2 paper, which uses the model in + combination with DPT. + size_divisor (`int`, *optional*): + If `do_pad` is `True`, pads the image dimensions to be divisible by this value. This was introduced in the + DINOv2 paper, which uses the model in combination with DPT. + prompt_scale_to_meter (`float`, *optional*, defaults to 0.001): + Scale factor to convert the prompt depth to meters. + """ + + model_input_names = ["pixel_values", "prompt_depth"] + valid_kwargs = PromptDepthAnythingImageProcessorKwargs + + def __init__( + self, + do_resize: bool = True, + size: dict[str, int] | None = None, + resample: PILImageResampling = PILImageResampling.BICUBIC, + keep_aspect_ratio: bool = False, + ensure_multiple_of: int = 1, + do_rescale: bool = True, + rescale_factor: int | float = 1 / 255, + do_normalize: bool = True, + image_mean: float | list[float] | None = None, + image_std: float | list[float] | None = None, + do_pad: bool = False, + size_divisor: int | None = None, + prompt_scale_to_meter: float = 0.001, # default unit is mm + **kwargs, + ): + super().__init__(**kwargs) + size = size if size is not None else {"height": 384, "width": 384} + size = get_size_dict(size) + self.do_resize = do_resize + self.size = size + self.keep_aspect_ratio = keep_aspect_ratio + self.ensure_multiple_of = ensure_multiple_of + self.resample = resample + self.do_rescale = do_rescale + self.rescale_factor = rescale_factor + self.do_normalize = do_normalize + self.image_mean = image_mean if image_mean is not None else IMAGENET_STANDARD_MEAN + self.image_std = image_std if image_std is not None else IMAGENET_STANDARD_STD + self.do_pad = do_pad + self.size_divisor = size_divisor + self.prompt_scale_to_meter = prompt_scale_to_meter + + def resize( + self, + image: np.ndarray, + size: dict[str, int], + keep_aspect_ratio: bool = False, + ensure_multiple_of: int = 1, + resample: PILImageResampling = PILImageResampling.BICUBIC, + data_format: str | ChannelDimension | None = None, + input_data_format: str | ChannelDimension | None = None, + **kwargs, + ) -> np.ndarray: + """ + Resize an image to target size `(size["height"], size["width"])`. If `keep_aspect_ratio` is `True`, the image + is resized to the largest possible size such that the aspect ratio is preserved. If `ensure_multiple_of` is + set, the image is resized to a size that is a multiple of this value. + + Args: + image (`np.ndarray`): + Image to resize. + size (`dict[str, int]`): + Target size of the output image. + keep_aspect_ratio (`bool`, *optional*, defaults to `False`): + If `True`, the image is resized to the largest possible size such that the aspect ratio is preserved. + ensure_multiple_of (`int`, *optional*, defaults to 1): + The image is resized to a size that is a multiple of this value. + resample (`PILImageResampling`, *optional*, defaults to `PILImageResampling.BICUBIC`): + Resampling filter to use when resiizing the image. + data_format (`str` or `ChannelDimension`, *optional*): + The channel dimension format of the image. If not provided, it will be the same as the input image. + input_data_format (`str` or `ChannelDimension`, *optional*): + The channel dimension format of the input image. If not provided, it will be inferred. + """ + size = get_size_dict(size) + if "height" not in size or "width" not in size: + raise ValueError(f"The size dictionary must contain the keys 'height' and 'width'. Got {size.keys()}") + + output_size = _get_resize_output_image_size( + image, + output_size=(size["height"], size["width"]), + keep_aspect_ratio=keep_aspect_ratio, + multiple=ensure_multiple_of, + input_data_format=input_data_format, + ) + return resize( + image, + size=output_size, + resample=resample, + data_format=data_format, + input_data_format=input_data_format, + **kwargs, + ) + + def pad_image( + self, + image: np.ndarray, + size_divisor: int, + data_format: str | ChannelDimension | None = None, + input_data_format: str | ChannelDimension | None = None, + ): + """ + Center pad an image to be a multiple of `multiple`. + + Args: + image (`np.ndarray`): + Image to pad. + size_divisor (`int`): + The width and height of the image will be padded to a multiple of this number. + data_format (`ChannelDimension` or `str`, *optional*, defaults to `ChannelDimension.FIRST`): + The channel dimension format for the output image. Can be one of: + - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format. + - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format. + - Unset: Use the channel dimension format of the input image. + input_data_format (`ChannelDimension` or `str`, *optional*): + The channel dimension format for the input image. If unset, the channel dimension format is inferred + from the input image. Can be one of: + - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format. + - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format. + - `"none"` or `ChannelDimension.NONE`: image in (height, width) format. + """ + + def _get_pad(size, size_divisor): + new_size = math.ceil(size / size_divisor) * size_divisor + pad_size = new_size - size + pad_size_left = pad_size // 2 + pad_size_right = pad_size - pad_size_left + return pad_size_left, pad_size_right + + if input_data_format is None: + input_data_format = infer_channel_dimension_format(image) + + height, width = get_image_size(image, input_data_format) + + pad_size_top, pad_size_bottom = _get_pad(height, size_divisor) + pad_size_left, pad_size_right = _get_pad(width, size_divisor) + + padded_image = pad( + image, ((pad_size_top, pad_size_bottom), (pad_size_left, pad_size_right)), data_format=data_format + ) + return padded_image + + @filter_out_non_signature_kwargs() + def preprocess( + self, + images: ImageInput, + prompt_depth: ImageInput | None = None, + do_resize: bool | None = None, + size: int | None = None, + keep_aspect_ratio: bool | None = None, + ensure_multiple_of: int | None = None, + resample: PILImageResampling | None = None, + do_rescale: bool | None = None, + rescale_factor: float | None = None, + do_normalize: bool | None = None, + image_mean: float | list[float] | None = None, + image_std: float | list[float] | None = None, + do_pad: bool | None = None, + size_divisor: int | None = None, + prompt_scale_to_meter: float | None = None, + return_tensors: str | TensorType | None = None, + data_format: ChannelDimension = ChannelDimension.FIRST, + input_data_format: str | ChannelDimension | None = None, + ) -> BatchFeature: + """ + Preprocess an image or batch of images. + + Args: + images (`ImageInput`): + Image to preprocess. Expects a single or batch of images with pixel values ranging from 0 to 255. If + passing in images with pixel values between 0 and 1, set `do_rescale=False`. + prompt_depth (`ImageInput`, *optional*): + Prompt depth to preprocess, which can be sparse depth obtained from multi-view geometry or + low-resolution depth from a depth sensor. Generally has shape (height, width), where height + and width can be smaller than those of the images. It's optional and can be None, which means no prompt depth + is used. If it is None, the output depth will be a monocular relative depth. + It is recommended to provide a prompt_scale_to_meter value, which is the scale factor to convert the prompt depth + to meters. This is useful when the prompt depth is not in meters. + do_resize (`bool`, *optional*, defaults to `self.do_resize`): + Whether to resize the image. + size (`dict[str, int]`, *optional*, defaults to `self.size`): + Size of the image after resizing. If `keep_aspect_ratio` is `True`, the image is resized to the largest + possible size such that the aspect ratio is preserved. If `ensure_multiple_of` is set, the image is + resized to a size that is a multiple of this value. + keep_aspect_ratio (`bool`, *optional*, defaults to `self.keep_aspect_ratio`): + Whether to keep the aspect ratio of the image. If False, the image will be resized to (size, size). If + True, the image will be resized to keep the aspect ratio and the size will be the maximum possible. + ensure_multiple_of (`int`, *optional*, defaults to `self.ensure_multiple_of`): + Ensure that the image size is a multiple of this value. + resample (`int`, *optional*, defaults to `self.resample`): + Resampling filter to use if resizing the image. This can be one of the enum `PILImageResampling`, Only + has an effect if `do_resize` is set to `True`. + do_rescale (`bool`, *optional*, defaults to `self.do_rescale`): + Whether to rescale the image values between [0 - 1]. + rescale_factor (`float`, *optional*, defaults to `self.rescale_factor`): + Rescale factor to rescale the image by if `do_rescale` is set to `True`. + do_normalize (`bool`, *optional*, defaults to `self.do_normalize`): + Whether to normalize the image. + image_mean (`float` or `list[float]`, *optional*, defaults to `self.image_mean`): + Image mean. + image_std (`float` or `list[float]`, *optional*, defaults to `self.image_std`): + Image standard deviation. + prompt_scale_to_meter (`float`, *optional*, defaults to `self.prompt_scale_to_meter`): + Scale factor to convert the prompt depth to meters. + return_tensors (`str` or `TensorType`, *optional*): + The type of tensors to return. Can be one of: + - Unset: Return a list of `np.ndarray`. + - `TensorType.PYTORCH` or `'pt'`: Return a batch of type `torch.Tensor`. + - `TensorType.NUMPY` or `'np'`: Return a batch of type `np.ndarray`. + data_format (`ChannelDimension` or `str`, *optional*, defaults to `ChannelDimension.FIRST`): + The channel dimension format for the output image. Can be one of: + - `ChannelDimension.FIRST`: image in (num_channels, height, width) format. + - `ChannelDimension.LAST`: image in (height, width, num_channels) format. + input_data_format (`ChannelDimension` or `str`, *optional*): + The channel dimension format for the input image. If unset, the channel dimension format is inferred + from the input image. Can be one of: + - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format. + - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format. + - `"none"` or `ChannelDimension.NONE`: image in (height, width) format. + """ + do_resize = do_resize if do_resize is not None else self.do_resize + size = size if size is not None else self.size + size = get_size_dict(size) + keep_aspect_ratio = keep_aspect_ratio if keep_aspect_ratio is not None else self.keep_aspect_ratio + ensure_multiple_of = ensure_multiple_of if ensure_multiple_of is not None else self.ensure_multiple_of + resample = resample if resample is not None else self.resample + do_rescale = do_rescale if do_rescale is not None else self.do_rescale + rescale_factor = rescale_factor if rescale_factor is not None else self.rescale_factor + do_normalize = do_normalize if do_normalize is not None else self.do_normalize + image_mean = image_mean if image_mean is not None else self.image_mean + image_std = image_std if image_std is not None else self.image_std + do_pad = do_pad if do_pad is not None else self.do_pad + size_divisor = size_divisor if size_divisor is not None else self.size_divisor + + images = make_flat_list_of_images(images) + + if not valid_images(images): + raise ValueError("Invalid image type. Must be of type PIL.Image.Image, numpy.ndarray, or torch.Tensor") + validate_preprocess_arguments( + do_rescale=do_rescale, + rescale_factor=rescale_factor, + do_normalize=do_normalize, + image_mean=image_mean, + image_std=image_std, + do_resize=do_resize, + size=size, + resample=resample, + ) + # All transformations expect numpy arrays. + images = [to_numpy_array(image) for image in images] + + if is_scaled_image(images[0]) and do_rescale: + logger.warning_once( + "It looks like you are trying to rescale already rescaled images. If the input" + " images have pixel values between 0 and 1, set `do_rescale=False` to avoid rescaling them again." + ) + + if input_data_format is None: + # We assume that all images have the same channel dimension format. + input_data_format = infer_channel_dimension_format(images[0]) + + preprocessed_images = [] + for image in images: + if do_resize: + image = self.resize( + image=image, + size=size, + resample=resample, + keep_aspect_ratio=keep_aspect_ratio, + ensure_multiple_of=ensure_multiple_of, + input_data_format=input_data_format, + ) + + if do_rescale: + image = self.rescale(image=image, scale=rescale_factor, input_data_format=input_data_format) + + if do_normalize: + image = self.normalize( + image=image, mean=image_mean, std=image_std, input_data_format=input_data_format + ) + + if do_pad: + image = self.pad_image(image=image, size_divisor=size_divisor, input_data_format=input_data_format) + + image = to_channel_dimension_format(image, data_format, input_channel_dim=input_data_format) + preprocessed_images.append(image) + + images = preprocessed_images + + data = {"pixel_values": images} + if prompt_depth is not None: + # prompt_depth is a list of images with shape (height, width) + # we need to convert it to a list of images with shape (1, height, width) + prompt_depths = make_flat_list_of_images(prompt_depth, expected_ndims=2) + + # Validate prompt_depths has same length as images + if len(prompt_depths) != len(images): + raise ValueError( + f"Number of prompt depth images ({len(prompt_depths)}) does not match number of input images ({len(images)})" + ) + + if prompt_scale_to_meter is None: + prompt_scale_to_meter = self.prompt_scale_to_meter + + processed_prompt_depths = [] + for depth in prompt_depths: + depth = to_numpy_array(depth) + depth = depth * prompt_scale_to_meter + if depth.min() == depth.max(): + # Prompt depth is invalid, min and max are the same. + # We can simply select one pixel and set it to a small value. + depth[0, 0] = depth[0, 0] + 1e-6 + depth = depth[..., None].astype(np.float32) + # Always use LAST as input format since we add channel dim with [..., None] + depth = to_channel_dimension_format(depth, data_format, input_channel_dim=ChannelDimension.LAST) + + processed_prompt_depths.append(depth) + prompt_depths = processed_prompt_depths + data["prompt_depth"] = prompt_depths + return BatchFeature(data=data, tensor_type=return_tensors) + + # Copied from transformers.models.dpt.image_processing_dpt.DPTImageProcessor.post_process_depth_estimation with DPT->PromptDepthAnything + def post_process_depth_estimation( + self, + outputs: "DepthEstimatorOutput", + target_sizes: TensorType | list[tuple[int, int]] | None | None = None, + ) -> list[dict[str, TensorType]]: + """ + Converts the raw output of [`DepthEstimatorOutput`] into final depth predictions and depth PIL images. + Only supports PyTorch. + + Args: + outputs ([`DepthEstimatorOutput`]): + Raw outputs of the model. + target_sizes (`TensorType` or `list[tuple[int, int]]`, *optional*): + Tensor of shape `(batch_size, 2)` or list of tuples (`tuple[int, int]`) containing the target size + (height, width) of each image in the batch. If left to None, predictions will not be resized. + + Returns: + `list[dict[str, TensorType]]`: A list of dictionaries of tensors representing the processed depth + predictions. + """ + requires_backends(self, "torch") + + predicted_depth = outputs.predicted_depth + + if (target_sizes is not None) and (len(predicted_depth) != len(target_sizes)): + raise ValueError( + "Make sure that you pass in as many target sizes as the batch dimension of the predicted depth" + ) + + results = [] + target_sizes = [None] * len(predicted_depth) if target_sizes is None else target_sizes + for depth, target_size in zip(predicted_depth, target_sizes): + if target_size is not None: + depth = torch.nn.functional.interpolate( + depth.unsqueeze(0).unsqueeze(1), size=target_size, mode="bicubic", align_corners=False + ).squeeze() + + results.append({"predicted_depth": depth}) + + return results + + +__all__ = ["PromptDepthAnythingImageProcessor"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/prompt_depth_anything/image_processing_prompt_depth_anything_fast.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/prompt_depth_anything/image_processing_prompt_depth_anything_fast.py new file mode 100644 index 0000000000000000000000000000000000000000..83a0c9994b1bbd90e352dcfe550a236f9a88a5fb --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/prompt_depth_anything/image_processing_prompt_depth_anything_fast.py @@ -0,0 +1,347 @@ +# Copyright 2025 The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""Fast Image processor class for PromptDepthAnything.""" + +import math +from typing import TYPE_CHECKING, Optional, Union + +from ...image_processing_utils import BatchFeature +from ...processing_utils import Unpack + + +if TYPE_CHECKING: + from ...modeling_outputs import DepthEstimatorOutput +import torch +import torchvision.transforms.v2.functional as tvF + +from ...image_processing_utils_fast import ( + BaseImageProcessorFast, + group_images_by_shape, + reorder_images, +) +from ...image_utils import ( + IMAGENET_STANDARD_MEAN, + IMAGENET_STANDARD_STD, + ChannelDimension, + ImageInput, + PILImageResampling, + SizeDict, +) +from ...utils import ( + TensorType, + auto_docstring, + requires_backends, +) +from .image_processing_prompt_depth_anything import PromptDepthAnythingImageProcessorKwargs + + +def _constrain_to_multiple_of(val, multiple, min_val=0, max_val=None): + """Constrain a value to be a multiple of another value.""" + x = round(val / multiple) * multiple + + if max_val is not None and x > max_val: + x = math.floor(val / multiple) * multiple + + if x < min_val: + x = math.ceil(val / multiple) * multiple + + return x + + +def _get_resize_output_image_size( + input_image: "torch.Tensor", + output_size: tuple[int, int], + keep_aspect_ratio: bool, + multiple: int, +) -> tuple[int, int]: + """Get the output size for resizing an image.""" + input_height, input_width = input_image.shape[-2:] + output_height, output_width = output_size + + # determine new height and width + scale_height = output_height / input_height + scale_width = output_width / input_width + + if keep_aspect_ratio: + # scale as little as possible + if abs(1 - scale_width) < abs(1 - scale_height): + # fit width + scale_height = scale_width + else: + # fit height + scale_width = scale_height + + new_height = _constrain_to_multiple_of(scale_height * input_height, multiple=multiple) + new_width = _constrain_to_multiple_of(scale_width * input_width, multiple=multiple) + + return (new_height, new_width) + + +@auto_docstring +class PromptDepthAnythingImageProcessorFast(BaseImageProcessorFast): + model_input_names = ["pixel_values", "prompt_depth"] + + resample = PILImageResampling.BICUBIC + image_mean = IMAGENET_STANDARD_MEAN + image_std = IMAGENET_STANDARD_STD + size = {"height": 384, "width": 384} + do_resize = True + do_rescale = True + do_normalize = True + keep_aspect_ratio = False + ensure_multiple_of = 1 + do_pad = False + size_divisor = None + prompt_scale_to_meter = 0.001 + valid_kwargs = PromptDepthAnythingImageProcessorKwargs + + def __init__(self, **kwargs: Unpack[PromptDepthAnythingImageProcessorKwargs]): + super().__init__(**kwargs) + + @auto_docstring + def preprocess( + self, + images: ImageInput, + prompt_depth: ImageInput | None = None, + **kwargs: Unpack[PromptDepthAnythingImageProcessorKwargs], + ) -> BatchFeature: + r""" + prompt_depth (`ImageInput`, *optional*): + Prompt depth to preprocess. + """ + return super().preprocess(images, prompt_depth, **kwargs) + + def resize_with_aspect_ratio( + self, + image: "torch.Tensor", + size: SizeDict, + keep_aspect_ratio: bool = False, + ensure_multiple_of: int = 1, + interpolation: Optional["tvF.InterpolationMode"] = None, + ) -> "torch.Tensor": + """ + Resize an image to target size while optionally maintaining aspect ratio and ensuring dimensions are multiples. + """ + # Set default interpolation to BICUBIC to match the slow processor (causes slight numerical differences otherwise) + if interpolation is None: + interpolation = tvF.InterpolationMode.BICUBIC + + # Custom resize with aspect ratio preservation and ensure_multiple_of constraint + output_size = _get_resize_output_image_size( + image, + output_size=(size["height"], size["width"]), + keep_aspect_ratio=keep_aspect_ratio, + multiple=ensure_multiple_of, + ) + + # Standard resize method with calculated output size + return self.resize( + image=image, + size=SizeDict(height=output_size[0], width=output_size[1]), + interpolation=interpolation, + ) + + def pad_image( + self, + image: "torch.Tensor", + size_divisor: int, + ) -> "torch.Tensor": + """ + Center pad an image to be a multiple of size_divisor. + """ + + def _get_pad(size, size_divisor): + new_size = math.ceil(size / size_divisor) * size_divisor + pad_size = new_size - size + pad_size_left = pad_size // 2 + pad_size_right = pad_size - pad_size_left + return pad_size_left, pad_size_right + + height, width = image.shape[-2:] + + # Match slow processor and PyTorch convention: width->left/right, height->top/bottom + pad_size_left, pad_size_right = _get_pad(width, size_divisor) + pad_size_top, pad_size_bottom = _get_pad(height, size_divisor) + + # Use torchvision padding for fast processing + # /!\ NB: torchvision tvF.pad expects (left, top, right, bottom) for the last two dims (W then H) + # Source: https://docs.pytorch.org/vision/main/generated/torchvision.transforms.Pad.html + # So: (left=width_pad, top=height_pad, right=width_pad, bottom=height_pad) + padding = [pad_size_left, pad_size_top, pad_size_right, pad_size_bottom] + padded_image = tvF.pad(image, padding=padding) + + return padded_image + + def _preprocess_image_like_inputs( + self, + images: ImageInput, + prompt_depth: ImageInput | None, + input_data_format: ChannelDimension, + device: Union[str, "torch.device"] | None = None, + prompt_scale_to_meter: float | None = None, + return_tensors: str | TensorType | None = None, + **kwargs: Unpack[PromptDepthAnythingImageProcessorKwargs], + ) -> BatchFeature: + """ + Preprocess image-like inputs, including the main images and optional prompt depth. + """ + images = self._prepare_image_like_inputs( + images=images, do_convert_rgb=False, input_data_format=input_data_format, device=device + ) # always use do_convert_rgb=False rather than defining it as a param to match slow processor + + # Process images with the standard pipeline + pixel_values = self._preprocess(images, return_tensors=return_tensors, **kwargs) + + data = {"pixel_values": pixel_values} + + # Process prompt depth if provided + if prompt_depth is not None: + processed_prompt_depths = self._prepare_image_like_inputs( + images=prompt_depth, + do_convert_rgb=False, # Depth maps should not be converted + input_data_format=input_data_format, + device=images[0].device if images else device, + expected_ndims=2, + ) + + # Validate prompt_depths has same length as images as in slow processor + if len(processed_prompt_depths) != len(images): + raise ValueError( + f"Number of prompt depth images ({len(processed_prompt_depths)}) does not match number of input images ({len(images)})" + ) + + final_prompt_depths = [] + for depth in processed_prompt_depths: + depth = depth * prompt_scale_to_meter + + # Handle case where depth is constant (min == max) + if depth.min() == depth.max(): + depth[0, 0] = depth[0, 0] + 1e-6 # Add small variation to avoid numerical issues + + if depth.ndim == 2: # Add channel dimension if needed + depth = depth.unsqueeze(0) # [H, W] -> [1, H, W] (channels first) + + depth = depth.float() # Convert to float32 to match slow processor + final_prompt_depths.append(depth) + + if return_tensors: + # Stack while preserving the [H, W, C] format that the slow processor uses + final_prompt_depths = torch.stack(final_prompt_depths, dim=0) + + data["prompt_depth"] = final_prompt_depths + + return BatchFeature(data=data, tensor_type=return_tensors) + + def _preprocess( + self, + images: list["torch.Tensor"], + do_resize: bool, + size: SizeDict, + keep_aspect_ratio: bool | None, + interpolation: Optional["tvF.InterpolationMode"], + do_rescale: bool, + rescale_factor: float, + do_normalize: bool, + image_mean: float | list[float] | None, + image_std: float | list[float] | None, + do_pad: bool | None, + disable_grouping: bool | None, + ensure_multiple_of: int | None = None, + return_tensors: str | TensorType | None = None, + size_divisor: int | None = None, + **kwargs, + ) -> "torch.Tensor": + """ + Override the base _preprocess method to handle custom PromptDepthAnything parameters. + """ + grouped_images, grouped_images_index = group_images_by_shape(images, disable_grouping=disable_grouping) + resized_images_grouped = {} + + for shape, stacked_images in grouped_images.items(): + if do_resize: + stacked_images = self.resize_with_aspect_ratio( + image=stacked_images, + size=size, + keep_aspect_ratio=keep_aspect_ratio, + ensure_multiple_of=ensure_multiple_of, + interpolation=interpolation, + ) + resized_images_grouped[shape] = stacked_images + + resized_images = reorder_images(resized_images_grouped, grouped_images_index) + + grouped_images, grouped_images_index = group_images_by_shape(resized_images, disable_grouping=disable_grouping) + processed_images_grouped = {} + + for shape, stacked_images in grouped_images.items(): + stacked_images = self.rescale_and_normalize( + stacked_images, do_rescale, rescale_factor, do_normalize, image_mean, image_std + ) + + if do_pad and size_divisor is not None: + stacked_images = self.pad_image(stacked_images, size_divisor) + + processed_images_grouped[shape] = stacked_images + + processed_images = reorder_images(processed_images_grouped, grouped_images_index) + + # Only stack tensors if they all have the same shape and return_tensors is specified + if return_tensors == "pt": + processed_images = torch.stack(processed_images, dim=0) + + return processed_images + + def post_process_depth_estimation( + self, + outputs: "DepthEstimatorOutput", + target_sizes: TensorType | list[tuple[int, int]] | None | None = None, + ) -> list[dict[str, TensorType]]: + """ + Converts the raw output of [`DepthEstimatorOutput`] into final depth predictions and depth PIL images. + Only supports PyTorch. + + Args: + outputs ([`DepthEstimatorOutput`]): + Raw outputs of the model. + target_sizes (`TensorType` or `list[tuple[int, int]]`, *optional*): + Tensor of shape `(batch_size, 2)` or list of tuples (`tuple[int, int]`) containing the target size + (height, width) of each image in the batch. If left to None, predictions will not be resized. + + Returns: + `list[dict[str, TensorType]]`: A list of dictionaries of tensors representing the processed depth + predictions. + """ + requires_backends(self, "torch") + + predicted_depth = outputs.predicted_depth + + if (target_sizes is not None) and (len(predicted_depth) != len(target_sizes)): + raise ValueError( + "Make sure that you pass in as many target sizes as the batch dimension of the predicted depth" + ) + + results = [] + target_sizes = [None] * len(predicted_depth) if target_sizes is None else target_sizes + for depth, target_size in zip(predicted_depth, target_sizes): + if target_size is not None: + depth = torch.nn.functional.interpolate( + depth.unsqueeze(0).unsqueeze(1), size=target_size, mode="bicubic", align_corners=False + ).squeeze() + + results.append({"predicted_depth": depth}) + + return results + + +__all__ = ["PromptDepthAnythingImageProcessorFast"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/prompt_depth_anything/modeling_prompt_depth_anything.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/prompt_depth_anything/modeling_prompt_depth_anything.py new file mode 100644 index 0000000000000000000000000000000000000000..5461d87c609a9fa02836cebbacf71e93386ee60f --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/prompt_depth_anything/modeling_prompt_depth_anything.py @@ -0,0 +1,498 @@ +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# This file was automatically generated from src/transformers/models/prompt_depth_anything/modular_prompt_depth_anything.py. +# Do NOT edit this file manually as any edits will be overwritten by the generation of +# the file from the modular. If any change should be done, please apply the change to the +# modular_prompt_depth_anything.py file directly. One of our CI enforces this. +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# Copyright 2025 The HuggingFace Team. All rights reserved. +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import torch +import torch.nn as nn + +from ...backbone_utils import load_backbone +from ...modeling_outputs import DepthEstimatorOutput +from ...modeling_utils import PreTrainedModel +from ...utils import auto_docstring +from ...utils.generic import torch_int +from .configuration_prompt_depth_anything import PromptDepthAnythingConfig + + +class PromptDepthAnythingLayer(nn.Module): + def __init__(self, config: PromptDepthAnythingConfig): + super().__init__() + self.convolution1 = nn.Conv2d( + 1, + config.fusion_hidden_size, + kernel_size=3, + stride=1, + padding=1, + bias=True, + ) + self.activation1 = nn.ReLU() + + self.convolution2 = nn.Conv2d( + config.fusion_hidden_size, + config.fusion_hidden_size, + kernel_size=3, + stride=1, + padding=1, + bias=True, + ) + self.activation2 = nn.ReLU() + + self.convolution3 = nn.Conv2d( + config.fusion_hidden_size, + config.fusion_hidden_size, + kernel_size=3, + stride=1, + padding=1, + bias=True, + ) + + def forward(self, prompt_depth: torch.Tensor) -> torch.Tensor: + hidden_state = self.convolution1(prompt_depth) + hidden_state = self.activation1(hidden_state) + hidden_state = self.convolution2(hidden_state) + hidden_state = self.activation2(hidden_state) + hidden_state = self.convolution3(hidden_state) + return hidden_state + + +class PromptDepthAnythingPreActResidualLayer(nn.Module): + """ + ResidualConvUnit, pre-activate residual unit. + + Args: + config (`[PromptDepthAnythingConfig]`): + Model configuration class defining the model architecture. + """ + + def __init__(self, config): + super().__init__() + + self.activation1 = nn.ReLU() + self.convolution1 = nn.Conv2d( + config.fusion_hidden_size, + config.fusion_hidden_size, + kernel_size=3, + stride=1, + padding=1, + bias=True, + ) + + self.activation2 = nn.ReLU() + self.convolution2 = nn.Conv2d( + config.fusion_hidden_size, + config.fusion_hidden_size, + kernel_size=3, + stride=1, + padding=1, + bias=True, + ) + + def forward(self, hidden_state: torch.Tensor) -> torch.Tensor: + residual = hidden_state + hidden_state = self.activation1(hidden_state) + hidden_state = self.convolution1(hidden_state) + hidden_state = self.activation2(hidden_state) + hidden_state = self.convolution2(hidden_state) + + return hidden_state + residual + + +class PromptDepthAnythingFeatureFusionLayer(nn.Module): + """Feature fusion layer, merges feature maps from different stages. + + Args: + config (`[PromptDepthAnythingConfig]`): + Model configuration class defining the model architecture. + """ + + def __init__(self, config: PromptDepthAnythingConfig): + super().__init__() + + self.projection = nn.Conv2d(config.fusion_hidden_size, config.fusion_hidden_size, kernel_size=1, bias=True) + + self.residual_layer1 = PromptDepthAnythingPreActResidualLayer(config) + self.residual_layer2 = PromptDepthAnythingPreActResidualLayer(config) + self.prompt_depth_layer = PromptDepthAnythingLayer(config) + + def forward(self, hidden_state, residual=None, size=None, prompt_depth=None): + if residual is not None: + if hidden_state.shape != residual.shape: + residual = nn.functional.interpolate( + residual, size=hidden_state.shape[2:], mode="bilinear", align_corners=False + ) + hidden_state = hidden_state + self.residual_layer1(residual) + + hidden_state = self.residual_layer2(hidden_state) + + if prompt_depth is not None: + prompt_depth = nn.functional.interpolate( + prompt_depth, size=hidden_state.shape[2:], mode="bilinear", align_corners=False + ) + res = self.prompt_depth_layer(prompt_depth) + hidden_state = hidden_state + res + + modifier = {"scale_factor": 2} if size is None else {"size": size} + + hidden_state = nn.functional.interpolate( + hidden_state, + **modifier, + mode="bilinear", + align_corners=True, + ) + hidden_state = self.projection(hidden_state) + + return hidden_state + + +class PromptDepthAnythingFeatureFusionStage(nn.Module): + def __init__(self, config: PromptDepthAnythingConfig): + super().__init__() + self.layers = nn.ModuleList() + for _ in range(len(config.neck_hidden_sizes)): + self.layers.append(PromptDepthAnythingFeatureFusionLayer(config)) + + def forward(self, hidden_states, size=None, prompt_depth=None): + # reversing the hidden_states, we start from the last + hidden_states = hidden_states[::-1] + + fused_hidden_states = [] + fused_hidden_state = None + + for idx, (hidden_state, layer) in enumerate(zip(hidden_states, self.layers)): + size = hidden_states[idx + 1].shape[2:] if idx != (len(hidden_states) - 1) else None + + if fused_hidden_state is None: + # first layer only uses the last hidden_state + fused_hidden_state = layer(hidden_state, size=size, prompt_depth=prompt_depth) + else: + fused_hidden_state = layer(fused_hidden_state, hidden_state, size=size, prompt_depth=prompt_depth) + + fused_hidden_states.append(fused_hidden_state) + + return fused_hidden_states + + +class PromptDepthAnythingDepthEstimationHead(nn.Module): + """ + Output head consisting of 3 convolutional layers. It progressively halves the feature dimension and upsamples + the predictions to the input resolution after the first convolutional layer (details can be found in the DPT paper's + supplementary material). The final activation function is either ReLU or Sigmoid, depending on the depth estimation + type (relative or metric). For metric depth estimation, the output is scaled by the maximum depth used during pretraining. + """ + + def __init__(self, config): + super().__init__() + + self.head_in_index = config.head_in_index + self.patch_size = config.patch_size + + features = config.fusion_hidden_size + self.conv1 = nn.Conv2d(features, features // 2, kernel_size=3, stride=1, padding=1) + self.conv2 = nn.Conv2d(features // 2, config.head_hidden_size, kernel_size=3, stride=1, padding=1) + self.activation1 = nn.ReLU() + self.conv3 = nn.Conv2d(config.head_hidden_size, 1, kernel_size=1, stride=1, padding=0) + if config.depth_estimation_type == "relative": + self.activation2 = nn.ReLU() + elif config.depth_estimation_type == "metric": + self.activation2 = nn.Sigmoid() + else: + raise ValueError(f"Unknown depth estimation type: {config.depth_estimation_type}") + self.max_depth = config.max_depth + + def forward(self, hidden_states: list[torch.Tensor], patch_height: int, patch_width: int) -> torch.Tensor: + hidden_states = hidden_states[-1] + + predicted_depth = self.conv1(hidden_states) + target_height = torch_int(patch_height * self.patch_size) + target_width = torch_int(patch_width * self.patch_size) + predicted_depth = nn.functional.interpolate( + predicted_depth, + (target_height, target_width), + mode="bilinear", + align_corners=True, + ) + predicted_depth = self.conv2(predicted_depth) + predicted_depth = self.activation1(predicted_depth) + predicted_depth = self.conv3(predicted_depth) + predicted_depth = self.activation2(predicted_depth) + # (batch_size, 1, height, width) -> (batch_size, height, width), which + # keeps the same behavior as Depth Anything v1 & v2 + predicted_depth = predicted_depth.squeeze(dim=1) + + return predicted_depth + + +@auto_docstring +class PromptDepthAnythingPreTrainedModel(PreTrainedModel): + config: PromptDepthAnythingConfig + base_model_prefix = "prompt_depth_anything" + main_input_name = "pixel_values" + input_modalities = ("image",) + supports_gradient_checkpointing = True + + +class PromptDepthAnythingReassembleLayer(nn.Module): + def __init__(self, config: PromptDepthAnythingConfig, channels: int, factor: int): + super().__init__() + self.projection = nn.Conv2d(in_channels=config.reassemble_hidden_size, out_channels=channels, kernel_size=1) + + # up/down sampling depending on factor + if factor > 1: + self.resize = nn.ConvTranspose2d(channels, channels, kernel_size=factor, stride=factor, padding=0) + elif factor == 1: + self.resize = nn.Identity() + elif factor < 1: + # so should downsample + stride = torch_int(1 / factor) + self.resize = nn.Conv2d(channels, channels, kernel_size=3, stride=stride, padding=1) + + def forward(self, hidden_state): + hidden_state = self.projection(hidden_state) + hidden_state = self.resize(hidden_state) + + return hidden_state + + +class PromptDepthAnythingReassembleStage(nn.Module): + """ + This class reassembles the hidden states of the backbone into image-like feature representations at various + resolutions. + + This happens in 3 stages: + 1. Take the patch embeddings and reshape them to image-like feature representations. + 2. Project the channel dimension of the hidden states according to `config.neck_hidden_sizes`. + 3. Resizing the spatial dimensions (height, width). + + Args: + config (`[PromptDepthAnythingConfig]`): + Model configuration class defining the model architecture. + """ + + def __init__(self, config): + super().__init__() + + self.config = config + self.layers = nn.ModuleList() + for channels, factor in zip(config.neck_hidden_sizes, config.reassemble_factors): + self.layers.append(PromptDepthAnythingReassembleLayer(config, channels=channels, factor=factor)) + + def forward(self, hidden_states: list[torch.Tensor], patch_height=None, patch_width=None) -> list[torch.Tensor]: + """ + Args: + hidden_states (`list[torch.FloatTensor]`, each of shape `(batch_size, sequence_length + 1, hidden_size)`): + List of hidden states from the backbone. + """ + out = [] + + for i, hidden_state in enumerate(hidden_states): + # reshape to (batch_size, num_channels, height, width) + hidden_state = hidden_state[:, 1:] + batch_size, _, num_channels = hidden_state.shape + hidden_state = hidden_state.reshape(batch_size, patch_height, patch_width, num_channels) + hidden_state = hidden_state.permute(0, 3, 1, 2).contiguous() + hidden_state = self.layers[i](hidden_state) + out.append(hidden_state) + + return out + + +class PromptDepthAnythingNeck(nn.Module): + """ + PromptDepthAnythingNeck. A neck is a module that is normally used between the backbone and the head. It takes a list of tensors as + input and produces another list of tensors as output. For PromptDepthAnything, it includes 2 stages: + + * PromptDepthAnythingReassembleStage + * PromptDepthAnythingFeatureFusionStage. + + Args: + config (dict): config dict. + """ + + def __init__(self, config): + super().__init__() + self.config = config + + self.reassemble_stage = PromptDepthAnythingReassembleStage(config) + + self.convs = nn.ModuleList() + for channel in config.neck_hidden_sizes: + self.convs.append(nn.Conv2d(channel, config.fusion_hidden_size, kernel_size=3, padding=1, bias=False)) + + # fusion + self.fusion_stage = PromptDepthAnythingFeatureFusionStage(config) + + def forward( + self, + hidden_states: list[torch.Tensor], + patch_height: int | None = None, + patch_width: int | None = None, + prompt_depth: torch.Tensor | None = None, + ) -> list[torch.Tensor]: + """ + Args: + hidden_states (`list[torch.FloatTensor]`, each of shape `(batch_size, sequence_length, hidden_size)` or `(batch_size, hidden_size, height, width)`): + List of hidden states from the backbone. + """ + if not isinstance(hidden_states, (tuple, list)): + raise TypeError("hidden_states should be a tuple or list of tensors") + + if len(hidden_states) != len(self.config.neck_hidden_sizes): + raise ValueError("The number of hidden states should be equal to the number of neck hidden sizes.") + + # postprocess hidden states + hidden_states = self.reassemble_stage(hidden_states, patch_height, patch_width) + + features = [self.convs[i](feature) for i, feature in enumerate(hidden_states)] + + # fusion blocks + output = self.fusion_stage(features, prompt_depth=prompt_depth) + + return output + + +@auto_docstring( + custom_intro=""" + Prompt Depth Anything Model with a depth estimation head on top (consisting of 3 convolutional layers) e.g. for KITTI, NYUv2. + """ +) +class PromptDepthAnythingForDepthEstimation(PromptDepthAnythingPreTrainedModel): + _no_split_modules = ["DPTViTEmbeddings"] + + def __init__(self, config): + super().__init__(config) + + self.backbone = load_backbone(config) + self.neck = PromptDepthAnythingNeck(config) + self.head = PromptDepthAnythingDepthEstimationHead(config) + + # Initialize weights and apply final processing + self.post_init() + + @auto_docstring + def forward( + self, + pixel_values: torch.FloatTensor, + prompt_depth: torch.FloatTensor | None = None, + labels: torch.LongTensor | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + **kwargs, + ) -> tuple[torch.Tensor] | DepthEstimatorOutput: + r""" + prompt_depth (`torch.FloatTensor` of shape `(batch_size, 1, height, width)`, *optional*): + Prompt depth is the sparse or low-resolution depth obtained from multi-view geometry or a + low-resolution depth sensor. It generally has shape (height, width), where height + and width can be smaller than those of the images. It is optional and can be None, which means no prompt depth + will be used. If it is None, the output will be a monocular relative depth. + The values are recommended to be in meters, but this is not necessary. + + Example: + + ```python + >>> from transformers import AutoImageProcessor, AutoModelForDepthEstimation + >>> import torch + >>> import numpy as np + >>> from PIL import Image + >>> import httpx + >>> from io import BytesIO + + >>> url = "https://github.com/DepthAnything/PromptDA/blob/main/assets/example_images/image.jpg?raw=true" + >>> with httpx.stream("GET", url) as response: + ... image = Image.open(BytesIO(response.read())) + + >>> image_processor = AutoImageProcessor.from_pretrained("depth-anything/prompt-depth-anything-vits-hf") + >>> model = AutoModelForDepthEstimation.from_pretrained("depth-anything/prompt-depth-anything-vits-hf") + + >>> prompt_depth_url = "https://github.com/DepthAnything/PromptDA/blob/main/assets/example_images/arkit_depth.png?raw=true" + >>> with httpx.stream("GET", prompt_depth_url) as response: + ... prompt_depth = Image.open(BytesIO(response.read())) + + >>> # prepare image for the model + >>> inputs = image_processor(images=image, return_tensors="pt", prompt_depth=prompt_depth) + + >>> with torch.no_grad(): + ... outputs = model(**inputs) + + >>> # interpolate to original size + >>> post_processed_output = image_processor.post_process_depth_estimation( + ... outputs, + ... target_sizes=[(image.height, image.width)], + ... ) + + >>> # visualize the prediction + >>> predicted_depth = post_processed_output[0]["predicted_depth"] + >>> depth = predicted_depth * 1000. + >>> depth = depth.detach().cpu().numpy() + >>> depth = Image.fromarray(depth.astype("uint16")) # mm + ``` + """ + loss = None + if labels is not None: + raise NotImplementedError("Training is not implemented yet") + + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + + outputs = self.backbone.forward_with_filtered_kwargs( + pixel_values, output_hidden_states=output_hidden_states, output_attentions=output_attentions + ) + hidden_states = outputs.feature_maps + + _, _, height, width = pixel_values.shape + patch_size = self.config.patch_size + patch_height = height // patch_size + patch_width = width // patch_size + + if prompt_depth is not None: + # normalize prompt depth + batch_size = prompt_depth.shape[0] + depth_min = torch.min(prompt_depth.reshape(batch_size, -1), dim=1).values + depth_max = torch.max(prompt_depth.reshape(batch_size, -1), dim=1).values + depth_min, depth_max = depth_min.view(batch_size, 1, 1, 1), depth_max.view(batch_size, 1, 1, 1) + prompt_depth = (prompt_depth - depth_min) / (depth_max - depth_min) + # normalize done + + hidden_states = self.neck(hidden_states, patch_height, patch_width, prompt_depth=prompt_depth) + + predicted_depth = self.head(hidden_states, patch_height, patch_width) + if prompt_depth is not None: + # denormalize predicted depth + depth_min = depth_min.squeeze(1).to(predicted_depth.device) + depth_max = depth_max.squeeze(1).to(predicted_depth.device) + predicted_depth = predicted_depth * (depth_max - depth_min) + depth_min + # denormalize done + + if not return_dict: + if output_hidden_states: + output = (predicted_depth,) + outputs[1:] + else: + output = (predicted_depth,) + outputs[2:] + return ((loss,) + output) if loss is not None else output + + return DepthEstimatorOutput( + loss=loss, + predicted_depth=predicted_depth, + hidden_states=outputs.hidden_states if output_hidden_states else None, + attentions=outputs.attentions, + ) + + +__all__ = ["PromptDepthAnythingForDepthEstimation", "PromptDepthAnythingPreTrainedModel"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/prompt_depth_anything/modular_prompt_depth_anything.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/prompt_depth_anything/modular_prompt_depth_anything.py new file mode 100644 index 0000000000000000000000000000000000000000..06f2cdab687a272dcdb38b1b46cbea17f8537995 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/prompt_depth_anything/modular_prompt_depth_anything.py @@ -0,0 +1,345 @@ +# Copyright 2025 The HuggingFace Team. All rights reserved. +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import torch +import torch.nn as nn + +from ...modeling_outputs import DepthEstimatorOutput +from ...modeling_utils import PreTrainedModel +from ...utils import auto_docstring +from ...utils.generic import torch_int +from ..depth_anything.configuration_depth_anything import DepthAnythingConfig +from ..depth_anything.modeling_depth_anything import ( + DepthAnythingDepthEstimationHead, + DepthAnythingFeatureFusionLayer, + DepthAnythingFeatureFusionStage, + DepthAnythingForDepthEstimation, + DepthAnythingNeck, + DepthAnythingReassembleStage, +) + + +class PromptDepthAnythingConfig(DepthAnythingConfig): + model_type = "prompt_depth_anything" + + +class PromptDepthAnythingLayer(nn.Module): + def __init__(self, config: PromptDepthAnythingConfig): + super().__init__() + self.convolution1 = nn.Conv2d( + 1, + config.fusion_hidden_size, + kernel_size=3, + stride=1, + padding=1, + bias=True, + ) + self.activation1 = nn.ReLU() + + self.convolution2 = nn.Conv2d( + config.fusion_hidden_size, + config.fusion_hidden_size, + kernel_size=3, + stride=1, + padding=1, + bias=True, + ) + self.activation2 = nn.ReLU() + + self.convolution3 = nn.Conv2d( + config.fusion_hidden_size, + config.fusion_hidden_size, + kernel_size=3, + stride=1, + padding=1, + bias=True, + ) + + def forward(self, prompt_depth: torch.Tensor) -> torch.Tensor: + hidden_state = self.convolution1(prompt_depth) + hidden_state = self.activation1(hidden_state) + hidden_state = self.convolution2(hidden_state) + hidden_state = self.activation2(hidden_state) + hidden_state = self.convolution3(hidden_state) + return hidden_state + + +class PromptDepthAnythingFeatureFusionLayer(DepthAnythingFeatureFusionLayer): + def __init__(self, config: PromptDepthAnythingConfig): + super().__init__(config) + self.prompt_depth_layer = PromptDepthAnythingLayer(config) + + def forward(self, hidden_state, residual=None, size=None, prompt_depth=None): + if residual is not None: + if hidden_state.shape != residual.shape: + residual = nn.functional.interpolate( + residual, size=hidden_state.shape[2:], mode="bilinear", align_corners=False + ) + hidden_state = hidden_state + self.residual_layer1(residual) + + hidden_state = self.residual_layer2(hidden_state) + + if prompt_depth is not None: + prompt_depth = nn.functional.interpolate( + prompt_depth, size=hidden_state.shape[2:], mode="bilinear", align_corners=False + ) + res = self.prompt_depth_layer(prompt_depth) + hidden_state = hidden_state + res + + modifier = {"scale_factor": 2} if size is None else {"size": size} + + hidden_state = nn.functional.interpolate( + hidden_state, + **modifier, + mode="bilinear", + align_corners=True, + ) + hidden_state = self.projection(hidden_state) + + return hidden_state + + +class PromptDepthAnythingFeatureFusionStage(DepthAnythingFeatureFusionStage): + def forward(self, hidden_states, size=None, prompt_depth=None): + # reversing the hidden_states, we start from the last + hidden_states = hidden_states[::-1] + + fused_hidden_states = [] + fused_hidden_state = None + + for idx, (hidden_state, layer) in enumerate(zip(hidden_states, self.layers)): + size = hidden_states[idx + 1].shape[2:] if idx != (len(hidden_states) - 1) else None + + if fused_hidden_state is None: + # first layer only uses the last hidden_state + fused_hidden_state = layer(hidden_state, size=size, prompt_depth=prompt_depth) + else: + fused_hidden_state = layer(fused_hidden_state, hidden_state, size=size, prompt_depth=prompt_depth) + + fused_hidden_states.append(fused_hidden_state) + + return fused_hidden_states + + +class PromptDepthAnythingDepthEstimationHead(DepthAnythingDepthEstimationHead): + def forward(self, hidden_states: list[torch.Tensor], patch_height: int, patch_width: int) -> torch.Tensor: + hidden_states = hidden_states[-1] + + predicted_depth = self.conv1(hidden_states) + target_height = torch_int(patch_height * self.patch_size) + target_width = torch_int(patch_width * self.patch_size) + predicted_depth = nn.functional.interpolate( + predicted_depth, + (target_height, target_width), + mode="bilinear", + align_corners=True, + ) + predicted_depth = self.conv2(predicted_depth) + predicted_depth = self.activation1(predicted_depth) + predicted_depth = self.conv3(predicted_depth) + predicted_depth = self.activation2(predicted_depth) + # (batch_size, 1, height, width) -> (batch_size, height, width), which + # keeps the same behavior as Depth Anything v1 & v2 + predicted_depth = predicted_depth.squeeze(dim=1) + + return predicted_depth + + +@auto_docstring +class PromptDepthAnythingPreTrainedModel(PreTrainedModel): + config: PromptDepthAnythingConfig + base_model_prefix = "prompt_depth_anything" + main_input_name = "pixel_values" + input_modalities = ("image",) + supports_gradient_checkpointing = True + + +class PromptDepthAnythingReassembleLayer(nn.Module): + def __init__(self, config: PromptDepthAnythingConfig, channels: int, factor: int): + super().__init__() + self.projection = nn.Conv2d(in_channels=config.reassemble_hidden_size, out_channels=channels, kernel_size=1) + + # up/down sampling depending on factor + if factor > 1: + self.resize = nn.ConvTranspose2d(channels, channels, kernel_size=factor, stride=factor, padding=0) + elif factor == 1: + self.resize = nn.Identity() + elif factor < 1: + # so should downsample + stride = torch_int(1 / factor) + self.resize = nn.Conv2d(channels, channels, kernel_size=3, stride=stride, padding=1) + + def forward(self, hidden_state): + hidden_state = self.projection(hidden_state) + hidden_state = self.resize(hidden_state) + + return hidden_state + + +class PromptDepthAnythingReassembleStage(DepthAnythingReassembleStage): + pass + + +class PromptDepthAnythingNeck(DepthAnythingNeck): + def forward( + self, + hidden_states: list[torch.Tensor], + patch_height: int | None = None, + patch_width: int | None = None, + prompt_depth: torch.Tensor | None = None, + ) -> list[torch.Tensor]: + """ + Args: + hidden_states (`list[torch.FloatTensor]`, each of shape `(batch_size, sequence_length, hidden_size)` or `(batch_size, hidden_size, height, width)`): + List of hidden states from the backbone. + """ + if not isinstance(hidden_states, (tuple, list)): + raise TypeError("hidden_states should be a tuple or list of tensors") + + if len(hidden_states) != len(self.config.neck_hidden_sizes): + raise ValueError("The number of hidden states should be equal to the number of neck hidden sizes.") + + # postprocess hidden states + hidden_states = self.reassemble_stage(hidden_states, patch_height, patch_width) + + features = [self.convs[i](feature) for i, feature in enumerate(hidden_states)] + + # fusion blocks + output = self.fusion_stage(features, prompt_depth=prompt_depth) + + return output + + +@auto_docstring( + custom_intro=""" + Prompt Depth Anything Model with a depth estimation head on top (consisting of 3 convolutional layers) e.g. for KITTI, NYUv2. + """ +) +class PromptDepthAnythingForDepthEstimation(DepthAnythingForDepthEstimation): + def forward( + self, + pixel_values: torch.FloatTensor, + prompt_depth: torch.FloatTensor | None = None, + labels: torch.LongTensor | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + **kwargs, + ) -> tuple[torch.Tensor] | DepthEstimatorOutput: + r""" + prompt_depth (`torch.FloatTensor` of shape `(batch_size, 1, height, width)`, *optional*): + Prompt depth is the sparse or low-resolution depth obtained from multi-view geometry or a + low-resolution depth sensor. It generally has shape (height, width), where height + and width can be smaller than those of the images. It is optional and can be None, which means no prompt depth + will be used. If it is None, the output will be a monocular relative depth. + The values are recommended to be in meters, but this is not necessary. + + Example: + + ```python + >>> from transformers import AutoImageProcessor, AutoModelForDepthEstimation + >>> import torch + >>> import numpy as np + >>> from PIL import Image + >>> import httpx + >>> from io import BytesIO + + >>> url = "https://github.com/DepthAnything/PromptDA/blob/main/assets/example_images/image.jpg?raw=true" + >>> with httpx.stream("GET", url) as response: + ... image = Image.open(BytesIO(response.read())) + + >>> image_processor = AutoImageProcessor.from_pretrained("depth-anything/prompt-depth-anything-vits-hf") + >>> model = AutoModelForDepthEstimation.from_pretrained("depth-anything/prompt-depth-anything-vits-hf") + + >>> prompt_depth_url = "https://github.com/DepthAnything/PromptDA/blob/main/assets/example_images/arkit_depth.png?raw=true" + >>> with httpx.stream("GET", prompt_depth_url) as response: + ... prompt_depth = Image.open(BytesIO(response.read())) + + >>> # prepare image for the model + >>> inputs = image_processor(images=image, return_tensors="pt", prompt_depth=prompt_depth) + + >>> with torch.no_grad(): + ... outputs = model(**inputs) + + >>> # interpolate to original size + >>> post_processed_output = image_processor.post_process_depth_estimation( + ... outputs, + ... target_sizes=[(image.height, image.width)], + ... ) + + >>> # visualize the prediction + >>> predicted_depth = post_processed_output[0]["predicted_depth"] + >>> depth = predicted_depth * 1000. + >>> depth = depth.detach().cpu().numpy() + >>> depth = Image.fromarray(depth.astype("uint16")) # mm + ``` + """ + loss = None + if labels is not None: + raise NotImplementedError("Training is not implemented yet") + + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + + outputs = self.backbone.forward_with_filtered_kwargs( + pixel_values, output_hidden_states=output_hidden_states, output_attentions=output_attentions + ) + hidden_states = outputs.feature_maps + + _, _, height, width = pixel_values.shape + patch_size = self.config.patch_size + patch_height = height // patch_size + patch_width = width // patch_size + + if prompt_depth is not None: + # normalize prompt depth + batch_size = prompt_depth.shape[0] + depth_min = torch.min(prompt_depth.reshape(batch_size, -1), dim=1).values + depth_max = torch.max(prompt_depth.reshape(batch_size, -1), dim=1).values + depth_min, depth_max = depth_min.view(batch_size, 1, 1, 1), depth_max.view(batch_size, 1, 1, 1) + prompt_depth = (prompt_depth - depth_min) / (depth_max - depth_min) + # normalize done + + hidden_states = self.neck(hidden_states, patch_height, patch_width, prompt_depth=prompt_depth) + + predicted_depth = self.head(hidden_states, patch_height, patch_width) + if prompt_depth is not None: + # denormalize predicted depth + depth_min = depth_min.squeeze(1).to(predicted_depth.device) + depth_max = depth_max.squeeze(1).to(predicted_depth.device) + predicted_depth = predicted_depth * (depth_max - depth_min) + depth_min + # denormalize done + + if not return_dict: + if output_hidden_states: + output = (predicted_depth,) + outputs[1:] + else: + output = (predicted_depth,) + outputs[2:] + return ((loss,) + output) if loss is not None else output + + return DepthEstimatorOutput( + loss=loss, + predicted_depth=predicted_depth, + hidden_states=outputs.hidden_states if output_hidden_states else None, + attentions=outputs.attentions, + ) + + +__all__ = [ + "PromptDepthAnythingConfig", + "PromptDepthAnythingForDepthEstimation", + "PromptDepthAnythingPreTrainedModel", +] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/prophetnet/__init__.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/prophetnet/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..7485dfbb530c3e11683c2b7dceaf35bf9edc9086 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/prophetnet/__init__.py @@ -0,0 +1,28 @@ +# Copyright 2024 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from typing import TYPE_CHECKING + +from ...utils import _LazyModule +from ...utils.import_utils import define_import_structure + + +if TYPE_CHECKING: + from .configuration_prophetnet import * + from .modeling_prophetnet import * + from .tokenization_prophetnet import * +else: + import sys + + _file = globals()["__file__"] + sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__) diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/prophetnet/configuration_prophetnet.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/prophetnet/configuration_prophetnet.py new file mode 100644 index 0000000000000000000000000000000000000000..c4747bc411f959016942fcc04a0a580987b03fa4 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/prophetnet/configuration_prophetnet.py @@ -0,0 +1,180 @@ +# Copyright 2020 The Microsoft Authors and The HuggingFace Inc. team. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""ProphetNet model configuration""" + +from collections.abc import Callable + +from ...configuration_utils import PreTrainedConfig +from ...utils import logging + + +logger = logging.get_logger(__name__) + + +class ProphetNetConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`ProphetNetModel`]. It is used to instantiate a + ProphetNet model according to the specified arguments, defining the model architecture. Instantiating a + configuration with the defaults will yield a similar configuration to that of the ProphetNet + [microsoft/prophetnet-large-uncased](https://huggingface.co/microsoft/prophetnet-large-uncased) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + activation_dropout (`float`, *optional*, defaults to 0.1): + The dropout ratio for activations inside the fully connected layer. + activation_function (`str` or `function`, *optional*, defaults to `"gelu"`): + The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`, + `"relu"`, `"silu"` and `"gelu_new"` are supported. + vocab_size (`int`, *optional*, defaults to 30522): + Vocabulary size of the ProphetNET model. Defines the number of different tokens that can be represented by + the `inputs_ids` passed when calling [`ProphetNetModel`]. + hidden_size (`int`, *optional*, defaults to 1024): + Dimensionality of the layers and the pooler layer. + encoder_ffn_dim (`int`, *optional*, defaults to 4096): + Dimensionality of the "intermediate" (often named feed-forward) layer in decoder. + num_encoder_layers (`int`, *optional*, defaults to 12): + Number of encoder layers. + num_encoder_attention_heads (`int`, *optional*, defaults to 16): + Number of attention heads for each attention layer in the Transformer encoder. + decoder_ffn_dim (`int`, *optional*, defaults to 4096): + Dimensionality of the `intermediate` (often named feed-forward) layer in decoder. + num_decoder_layers (`int`, *optional*, defaults to 12): + Number of decoder layers. + num_decoder_attention_heads (`int`, *optional*, defaults to 16): + Number of attention heads for each attention layer in the Transformer decoder. + attention_dropout (`float`, *optional*, defaults to 0.1): + The dropout ratio for the attention probabilities. + dropout (`float`, *optional*, defaults to 0.1): + The dropout probability for all fully connected layers in the embeddings, encoder, and pooler. + max_position_embeddings (`int`, *optional*, defaults to 512): + The maximum sequence length that this model might ever be used with. Typically set this to something large + just in case (e.g., 512 or 1024 or 2048). + init_std (`float`, *optional*, defaults to 0.02): + The standard deviation of the truncated_normal_initializer for initializing all weight matrices. + add_cross_attention (`bool`, *optional*, defaults to `True`): + Whether cross-attention layers should be added to the model. + is_encoder_decoder (`bool`, *optional*, defaults to `True`): + Whether this is an encoder/decoder model. + pad_token_id (`int`, *optional*, defaults to 1) + Padding token id. + bos_token_id (`int`, *optional*, defaults to 0) + Beginning of stream token id. + eos_token_id (`int`, *optional*, defaults to 2) + End of stream token id. + ngram (`int`, *optional*, defaults to 2) + Number of future tokens to predict. Set to 1 to be same as traditional Language model to predict next first + token. + num_buckets (`int`, *optional*, defaults to 32) + The number of buckets to use for each attention layer. This is for relative position calculation. See the + [T5 paper](see https://huggingface.co/papers/1910.10683) for more details. + relative_max_distance (`int`, *optional*, defaults to 128) + Relative distances greater than this number will be put into the last same bucket. This is for relative + position calculation. See the [T5 paper](see https://huggingface.co/papers/1910.10683) for more details. + disable_ngram_loss (`bool`, *optional*, defaults to `False`): + Whether be trained predicting only the next first token. + eps (`float`, *optional*, defaults to 0.0): + Controls the `epsilon` parameter value for label smoothing in the loss calculation. If set to 0, no label + smoothing is performed. + use_cache (`bool`, *optional*, defaults to `True`): + Whether or not the model should return the last key/values attentions (not used by all models). + """ + + model_type = "prophetnet" + keys_to_ignore_at_inference = ["past_key_values"] + attribute_map = { + "num_attention_heads": "num_encoder_attention_heads", + } + + def __init__( + self, + activation_dropout: float | None = 0.1, + activation_function: str | Callable | None = "gelu", + vocab_size: int | None = 30522, + hidden_size: int | None = 1024, + encoder_ffn_dim: int | None = 4096, + num_encoder_layers: int | None = 12, + num_encoder_attention_heads: int | None = 16, + decoder_ffn_dim: int | None = 4096, + num_decoder_layers: int | None = 12, + num_decoder_attention_heads: int | None = 16, + attention_dropout: float | None = 0.1, + dropout: float | None = 0.1, + max_position_embeddings: int | None = 512, + init_std: float | None = 0.02, + is_encoder_decoder: bool | None = True, + add_cross_attention: bool | None = True, + decoder_start_token_id: int | None = 0, + ngram: int | None = 2, + num_buckets: int | None = 32, + relative_max_distance: int | None = 128, + disable_ngram_loss: bool | None = False, + eps: float | None = 0.0, + use_cache: bool | None = True, + pad_token_id: int | None = 0, + bos_token_id: int | None = 1, + eos_token_id: int | None = 2, + is_decoder: bool | None = False, + tie_word_embeddings: bool | None = True, + **kwargs, + ): + self.vocab_size = vocab_size + self.hidden_size = hidden_size + self.encoder_ffn_dim = encoder_ffn_dim + self.num_encoder_layers = num_encoder_layers + self.num_encoder_attention_heads = num_encoder_attention_heads + self.decoder_ffn_dim = decoder_ffn_dim + self.num_decoder_layers = num_decoder_layers + self.num_decoder_attention_heads = num_decoder_attention_heads + self.max_position_embeddings = max_position_embeddings + self.init_std = init_std # Normal(0, this parameter) + self.activation_function = activation_function + + # parameters for prophetnet + self.ngram = ngram + self.num_buckets = num_buckets + self.relative_max_distance = relative_max_distance + self.disable_ngram_loss = disable_ngram_loss + self.eps = eps + + # 3 Types of Dropout + self.attention_dropout = attention_dropout + self.activation_dropout = activation_dropout + self.dropout = dropout + + self.use_cache = use_cache + self.pad_token_id = pad_token_id + self.bos_token_id = bos_token_id + self.eos_token_id = eos_token_id + self.add_cross_attention = add_cross_attention + self.decoder_start_token_id = decoder_start_token_id + self.is_decoder = is_decoder + self.tie_word_embeddings = tie_word_embeddings + + super().__init__(is_encoder_decoder=is_encoder_decoder, **kwargs) + + @property + def num_hidden_layers(self) -> int: + return self.num_encoder_layers + + @num_hidden_layers.setter + def num_hidden_layers(self, value): + raise NotImplementedError( + "This model does not support the setting of `num_hidden_layers`. Please set `num_encoder_layers` and" + " `num_decoder_layers`." + ) + + +__all__ = ["ProphetNetConfig"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/prophetnet/modeling_prophetnet.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/prophetnet/modeling_prophetnet.py new file mode 100644 index 0000000000000000000000000000000000000000..c8b8db547a7cacfc6c861031a85b1df7aaa13c59 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/prophetnet/modeling_prophetnet.py @@ -0,0 +1,1879 @@ +# Copyright 2020 The Microsoft Authors and The HuggingFace Inc. team. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""PyTorch ProphetNet model, ported from ProphetNet repo(fairsequery_states version).""" + +import copy +import math +from dataclasses import dataclass + +import torch +from torch import Tensor, nn +from torch.nn import LayerNorm + +from ...activations import ACT2FN +from ...cache_utils import Cache, DynamicCache, EncoderDecoderCache +from ...generation import GenerationMixin +from ...modeling_layers import GradientCheckpointingLayer +from ...modeling_outputs import BaseModelOutput +from ...modeling_utils import PreTrainedModel +from ...utils import ModelOutput, auto_docstring, logging +from .configuration_prophetnet import ProphetNetConfig + + +logger = logging.get_logger(__name__) + + +def softmax(hidden_state, dim, onnx_trace=False): + if onnx_trace: + return nn.functional.softmax(hidden_state.float(), dim=dim) + else: + return nn.functional.softmax(hidden_state, dim=dim, dtype=torch.float32) + + +def ngram_attention_bias(sequence_length, ngram, device, dtype): + """ + This function computes the bias for the predict stream + """ + left_block = ( + torch.ones((ngram, sequence_length, sequence_length), device=device, dtype=dtype) * torch.finfo(dtype).min + ) + right_block = left_block.detach().clone() + # create bias + for stream_idx in range(ngram): + right_block[stream_idx].fill_diagonal_(0, wrap=False) + left_block[stream_idx].triu_(-stream_idx + 1) + + left_block[:, :, 0] = 0 + return torch.cat([left_block, right_block], dim=2) + + +def compute_relative_buckets(num_buckets, max_distance, relative_positions, is_bidirectional=False): + """ + This function computes individual parts of the relative position buckets. For more detail, see paper. + """ + inv_relative_positions = -relative_positions + rel_positions_bucket = 0 + + if is_bidirectional: + num_buckets = num_buckets // 2 + rel_positions_bucket = ( + rel_positions_bucket + + torch.lt(inv_relative_positions, torch.zeros_like(inv_relative_positions)).int() * num_buckets + ) + inv_relative_positions = torch.abs(inv_relative_positions) + else: + inv_relative_positions = torch.max(inv_relative_positions, torch.zeros_like(inv_relative_positions)) + + max_exact = num_buckets // 2 + is_small = torch.lt(inv_relative_positions, max_exact) + val_if_large = max_exact + torch.log(inv_relative_positions.float() / max_exact) / math.log( + max_distance / max_exact + ) * (num_buckets - max_exact) + val_if_large = torch.min(val_if_large, torch.ones_like(val_if_large) * (num_buckets - 1)).int() + rel_positions_bucket = rel_positions_bucket + torch.where(is_small, inv_relative_positions.int(), val_if_large) + return rel_positions_bucket + + +def compute_all_stream_relative_buckets(num_buckets, max_distance, position_ids): + """ + This function computes both main and predict relative position buckets. For more detail, see paper. + """ + # main stream + main_stream_relative_positions = position_ids.unsqueeze(1).repeat(1, position_ids.size(-1), 1) + main_stream_relative_positions = main_stream_relative_positions - position_ids.unsqueeze(-1) + + # predicting stream + predicting_stream_relative_positions = torch.cat((position_ids - 1, position_ids), dim=-1).unsqueeze(1) + predicting_stream_relative_positions = predicting_stream_relative_positions.repeat(1, position_ids.size(-1), 1) + predicting_stream_relative_positions = predicting_stream_relative_positions - position_ids.unsqueeze(-1) + + # get both position buckets + main_relative_position_buckets = compute_relative_buckets( + num_buckets, max_distance, main_stream_relative_positions, is_bidirectional=False + ) + predict_relative_position_buckets = compute_relative_buckets( + num_buckets, max_distance, predicting_stream_relative_positions, is_bidirectional=False + ) + return main_relative_position_buckets, predict_relative_position_buckets + + +@dataclass +@auto_docstring( + custom_intro=""" + Base class for sequence-to-sequence language models outputs. + """ +) +class ProphetNetSeq2SeqLMOutput(ModelOutput): + r""" + loss (`torch.FloatTensor` of shape `(1,)`, *optional*, returned when `labels` is provided): + Language modeling loss. + logits (`torch.FloatTensor` of shape `(batch_size, decoder_sequence_length, config.vocab_size)`): + Prediction scores of the main stream language modeling head (scores for each vocabulary token before + SoftMax). + logits_ngram (`torch.FloatTensor` of shape `(batch_size, ngram * decoder_sequence_length, config.vocab_size)`): + Prediction scores of the predict stream language modeling head (scores for each vocabulary token before + SoftMax). + past_key_values (`Cache`, *optional*, returned when `use_cache=True` is passed or when `config.use_cache=True`): + It is a [`~cache_utils.Cache`] instance. For more details, see our [kv cache guide](https://huggingface.co/docs/transformers/en/kv_cache). + + Contains pre-computed hidden-states (key and values in the attention blocks) of the decoder that can be + used (see `past_key_values` input) to speed up sequential decoding. + decoder_ngram_hidden_states (`tuple(torch.FloatTensor)`, *optional*, returned when `output_hidden_states=True` is passed or when `config.output_hidden_states=True`): + Tuple of `torch.FloatTensor` (one for the output of the embeddings + one for the output of each layer) of + shape `(batch_size, ngram * decoder_sequence_length, hidden_size)`. + + Hidden-states of the predict stream of the decoder at the output of each layer plus the initial embedding + outputs. + decoder_ngram_attentions (`tuple(torch.FloatTensor)`, *optional*, returned when `output_attentions=True` is passed or when `config.output_attentions=True`): + Tuple of `torch.FloatTensor` (one for each layer) of shape `(batch_size, num_attn_heads, + decoder_sequence_length, decoder_sequence_length)`. + + Attentions weights of the predict stream of the decoder, after the attention softmax, used to compute the + weighted average in the self-attention heads. + encoder_last_hidden_state (`torch.FloatTensor` of shape `(batch_size, encoder_sequence_length, hidden_size)`, *optional*): + Sequence of hidden-states at the output of the last layer of the encoder of the model. + """ + + loss: torch.FloatTensor | None = None + logits: torch.FloatTensor | None = None + logits_ngram: torch.FloatTensor | None = None + past_key_values: Cache | None = None + decoder_hidden_states: tuple[torch.FloatTensor] | None = None + decoder_ngram_hidden_states: tuple[torch.FloatTensor] | None = None + decoder_attentions: tuple[torch.FloatTensor] | None = None + decoder_ngram_attentions: tuple[torch.FloatTensor] | None = None + cross_attentions: tuple[torch.FloatTensor] | None = None + encoder_last_hidden_state: torch.FloatTensor | None = None + encoder_hidden_states: tuple[torch.FloatTensor] | None = None + encoder_attentions: tuple[torch.FloatTensor] | None = None + + +@dataclass +@auto_docstring( + custom_intro=""" + Base class for model encoder's outputs that also contains : pre-computed hidden states that can speed up sequential + decoding. + """ +) +class ProphetNetSeq2SeqModelOutput(ModelOutput): + r""" + last_hidden_state (`torch.FloatTensor` of shape `(batch_size, decoder_sequence_length, hidden_size)`): + Sequence of main stream hidden-states at the output of the last layer of the decoder of the model. + + If `past_key_values` is used only the last hidden-state of the sequences of shape `(batch_size, 1, + hidden_size)` is output. + last_hidden_state_ngram (`torch.FloatTensor` of shape `(batch_size,ngram * decoder_sequence_length, config.vocab_size)`, *optional*): + Sequence of predict stream hidden-states at the output of the last layer of the decoder of the model. + past_key_values (`Cache`, *optional*, returned when `use_cache=True` is passed or when `config.use_cache=True`): + It is a [`~cache_utils.Cache`] instance. For more details, see our [kv cache guide](https://huggingface.co/docs/transformers/en/kv_cache). + + Contains pre-computed hidden-states (key and values in the attention blocks) of the decoder that can be + used (see `past_key_values` input) to speed up sequential decoding. + decoder_ngram_hidden_states (`tuple(torch.FloatTensor)`, *optional*, returned when `output_hidden_states=True` is passed or when `config.output_hidden_states=True`): + Tuple of `torch.FloatTensor` (one for the output of the embeddings + one for the output of each layer) of + shape `(batch_size, ngram * decoder_sequence_length, hidden_size)`. + + Hidden-states of the predict stream of the decoder at the output of each layer plus the initial embedding + outputs. + decoder_ngram_attentions (`tuple(torch.FloatTensor)`, *optional*, returned when `output_attentions=True` is passed or when `config.output_attentions=True`): + Tuple of `torch.FloatTensor` (one for each layer) of shape `(batch_size, num_attn_heads, + decoder_sequence_length, decoder_sequence_length)`. + + Attentions weights of the predict stream of the decoder, after the attention softmax, used to compute the + weighted average in the + encoder_last_hidden_state (`torch.FloatTensor` of shape `(batch_size, encoder_sequence_length, hidden_size)`, *optional*): + Sequence of hidden-states at the output of the last layer of the encoder of the model. + """ + + last_hidden_state: torch.FloatTensor + last_hidden_state_ngram: torch.FloatTensor | None = None + past_key_values: Cache | None = None + decoder_hidden_states: tuple[torch.FloatTensor] | None = None + decoder_ngram_hidden_states: tuple[torch.FloatTensor] | None = None + decoder_attentions: tuple[torch.FloatTensor] | None = None + decoder_ngram_attentions: tuple[torch.FloatTensor] | None = None + cross_attentions: tuple[torch.FloatTensor] | None = None + encoder_last_hidden_state: torch.FloatTensor | None = None + encoder_hidden_states: tuple[torch.FloatTensor] | None = None + encoder_attentions: tuple[torch.FloatTensor] | None = None + + +@dataclass +@auto_docstring( + custom_intro=""" + Base class for model's outputs that may also contain a past key/values (to speed up sequential decoding). + """ +) +class ProphetNetDecoderModelOutput(ModelOutput): + r""" + last_hidden_state (`torch.FloatTensor` of shape `(batch_size, decoder_sequence_length, hidden_size)`): + Sequence of main stream hidden-states at the output of the last layer of the decoder of the model. + + If `past_key_values` is used only the last hidden-state of the sequences of shape `(batch_size, 1, + hidden_size)` is output. + last_hidden_state_ngram (`torch.FloatTensor` of shape `(batch_size, ngram * decoder_sequence_length, config.vocab_size)`): + Sequence of predict stream hidden-states at the output of the last layer of the decoder of the model. + past_key_values (`Cache`, *optional*, returned when `use_cache=True` is passed or when `config.use_cache=True`): + It is a [`~cache_utils.Cache`] instance. For more details, see our [kv cache guide](https://huggingface.co/docs/transformers/en/kv_cache). + + Contains pre-computed hidden-states (key and values in the attention blocks) of the decoder that can be + used (see `past_key_values` input) to speed up sequential decoding. + hidden_states_ngram (`tuple(torch.FloatTensor)`, *optional*, returned when `output_hidden_states=True` is passed or when `config.output_hidden_states=True`): + Tuple of `torch.FloatTensor` (one for the output of the embeddings + one for the output of each layer) of + shape `(batch_size, ngram * decoder_sequence_length, hidden_size)`. + + Hidden-states of the predict stream of the decoder at the output of each layer plus the initial embedding + outputs. + ngram_attentions (`tuple(torch.FloatTensor)`, *optional*, returned when `output_attentions=True` is passed or when `config.output_attentions=True`): + Tuple of `torch.FloatTensor` (one for each layer) of shape `(batch_size, num_attn_heads, + decoder_sequence_length, decoder_sequence_length)`. + + Attentions weights of the predict stream of the decoder, after the attention softmax, used to compute the + weighted average in the + """ + + last_hidden_state: torch.FloatTensor + last_hidden_state_ngram: torch.FloatTensor | None = None + past_key_values: Cache | None = None + hidden_states: tuple[torch.FloatTensor] | None = None + hidden_states_ngram: tuple[torch.FloatTensor] | None = None + attentions: tuple[torch.FloatTensor] | None = None + ngram_attentions: tuple[torch.FloatTensor] | None = None + cross_attentions: tuple[torch.FloatTensor] | None = None + + +@dataclass +@auto_docstring( + custom_intro=""" + Base class for model's outputs that may also contain a past key/values (to speed up sequential decoding). + """ +) +class ProphetNetDecoderLMOutput(ModelOutput): + r""" + ngram_hidden_states (`tuple(torch.FloatTensor)`, *optional*, returned when `output_hidden_states=True` is passed or when `config.output_hidden_states=True`): + Tuple of `torch.FloatTensor` (one for the output of the embeddings + one for the output of each layer) of + shape `(batch_size, ngram * decoder_sequence_length, hidden_size)`. + + Hidden-states of the predict stream of the decoder at the output of each layer plus the initial embedding + outputs. + loss (`torch.FloatTensor` of shape `(1,)`, *optional*, returned when `labels` is provided): + Language modeling loss. + logits (`torch.FloatTensor` of shape `(batch_size, decoder_sequence_length, config.vocab_size)`): + Prediction scores of the main stream language modeling head (scores for each vocabulary token before + SoftMax). + logits_ngram (`torch.FloatTensor` of shape `(batch_size, ngram * decoder_sequence_length, config.vocab_size)`): + Prediction scores of the predict stream language modeling head (scores for each vocabulary token before + SoftMax). + past_key_values (`Cache`, *optional*, returned when `use_cache=True` is passed or when `config.use_cache=True`): + It is a [`~cache_utils.Cache`] instance. For more details, see our [kv cache guide](https://huggingface.co/docs/transformers/en/kv_cache). + + Contains pre-computed hidden-states (key and values in the attention blocks) of the decoder that can be + used (see `past_key_values` input) to speed up sequential decoding. + hidden_states_ngram (`tuple(torch.FloatTensor)`, *optional*, returned when `output_hidden_states=True` is passed or when `config.output_hidden_states=True`): + Tuple of `torch.FloatTensor` (one for the output of the embeddings + one for the output of each layer) of + shape `(batch_size, ngram * decoder_sequence_length, hidden_size)`. + + Hidden-states of the predict stream of the decoder at the output of each layer plus the initial embedding + outputs. + ngram_attentions (`tuple(torch.FloatTensor)`, *optional*, returned when `output_attentions=True` is passed or when `config.output_attentions=True`): + Tuple of `torch.FloatTensor` (one for each layer) of shape `(batch_size, num_attn_heads, + decoder_sequence_length, decoder_sequence_length)`. + + Attentions weights of the predict stream of the decoder, after the attention softmax, used to compute the + weighted average in the + """ + + loss: torch.FloatTensor | None = None + logits: torch.FloatTensor | None = None + logits_ngram: torch.FloatTensor | None = None + past_key_values: Cache | None = None + hidden_states: tuple[torch.FloatTensor] | None = None + hidden_states_ngram: tuple[torch.FloatTensor] | None = None + attentions: tuple[torch.FloatTensor] | None = None + ngram_attentions: tuple[torch.FloatTensor] | None = None + cross_attentions: tuple[torch.FloatTensor] | None = None + + +@auto_docstring +class ProphetNetPreTrainedModel(PreTrainedModel): + config: ProphetNetConfig + base_model_prefix = "prophetnet" + supports_gradient_checkpointing = True + + def _shift_right(self, input_ids): + decoder_start_token_id = self.config.decoder_start_token_id + pad_token_id = self.config.pad_token_id + + assert decoder_start_token_id is not None, ( + "self.model.config.decoder_start_token_id has to be defined. In ProphetNet it is usually set to the" + " pad_token_id. See ProphetNet docs for more information" + ) + + # shift inputs to the right + shifted_input_ids = input_ids.new_zeros(input_ids.shape) + shifted_input_ids[..., 1:] = input_ids[..., :-1].clone() + shifted_input_ids[..., 0] = decoder_start_token_id + + assert pad_token_id is not None, "self.model.config.pad_token_id has to be defined." + # replace possible -100 values in labels by `pad_token_id` + shifted_input_ids.masked_fill_(shifted_input_ids == -100, pad_token_id) + + assert torch.all(shifted_input_ids >= 0).item(), "Verify that `shifted_input_ids` has only positive values" + + return shifted_input_ids + + +class ProphetNetPositionalEmbeddings(nn.Embedding): + """ + This module learns positional embeddings up to a fixed maximum size. Padding ids are ignored by either offsetting + based on padding_idx or by setting padding_idx to None and ensuring that the appropriate position ids are passed to + the forward function. + """ + + def __init__(self, config: ProphetNetConfig) -> None: + self.max_length = config.max_position_embeddings + super().__init__(config.max_position_embeddings, config.hidden_size, config.pad_token_id) + + def forward(self, inputs_shape, device, attention_mask=None, past_key_values=None, position_ids=None): + assert (position_ids is None) or (self.padding_idx is None), ( + "If position_ids is pre-computed then padding_idx should not be set." + ) + + if position_ids is None: + if past_key_values is not None and past_key_values.get_seq_length() != 0: + # position_ids is the same for every token when decoding a single step + # Without the int() cast, it doesn't work in some cases when exporting to ONNX + prev_num_input_ids = past_key_values.get_seq_length() + num_input_ids = inputs_shape[1] + prev_num_input_ids + position_ids = torch.ones((1, 1), dtype=torch.long, device=device) * ( + int(self.padding_idx + num_input_ids) + ) + else: + if attention_mask is None: + attention_mask = torch.ones(inputs_shape, dtype=torch.long, device=device) + + # retrieve position_ids from input_ids / attention_mask + position_ids = ( + torch.cumsum(attention_mask, dim=1).type_as(attention_mask) * attention_mask + ).long() + self.padding_idx + + # make sure position_ids are not bigger then max_length + position_ids = position_ids.clamp(0, self.max_length - 1) + + return super().forward(position_ids), position_ids + + def _forward(self, position_ids): + return super().forward(position_ids) + + +class ProphetNetAttention(nn.Module): + """Multi-headed attention from 'Attention Is All You Need' paper""" + + def __init__(self, config: ProphetNetConfig, num_attn_heads: int, layer_idx: int | None = None): + super().__init__() + hidden_size = config.hidden_size + + self.attention_dropout = config.attention_dropout + self.dropout = config.dropout + self.num_attn_heads = num_attn_heads + self.head_dim = hidden_size // num_attn_heads + self.layer_idx = layer_idx + + assert self.head_dim * num_attn_heads == hidden_size, ( + "`config.hidden_size` must be divisible by `config.num_encoder_attention_heads` and" + " `config.num_decoder_attention_heads`" + ) + + self.key_proj = nn.Linear(hidden_size, hidden_size) + self.value_proj = nn.Linear(hidden_size, hidden_size) + self.query_proj = nn.Linear(hidden_size, hidden_size) + + self.out_proj = nn.Linear(hidden_size, hidden_size) + + def forward( + self, + hidden_states, + key_value_states: Tensor | None = None, + attention_mask: Tensor | None = None, + past_key_values: Cache | None = None, + output_attentions: bool | None = False, + cache_position: torch.Tensor | None = None, + ) -> tuple[Tensor, Tensor | None]: + batch_size, tgt_len, hidden_size = hidden_states.size() + + # if key_value_states are provided this layer is used as a cross-attention layer + # for the decoder + is_cross_attention = key_value_states is not None + assert list(hidden_states.size()) == [ + batch_size, + tgt_len, + hidden_size, + ], f"Size of hidden states should be {batch_size, tgt_len, hidden_size}, but is {hidden_states.size()}" + + # previous time steps are cached - no need to recompute key and value if they are static + query_states = self.query_proj(hidden_states) / (self.head_dim**0.5) + + is_updated = False + if past_key_values is not None: + if isinstance(past_key_values, EncoderDecoderCache): + is_updated = past_key_values.is_updated.get(self.layer_idx) + if is_cross_attention: + # after the first generated id, we can subsequently re-use all key/value_states from cache + curr_past_key_values = past_key_values.cross_attention_cache + else: + curr_past_key_values = past_key_values.self_attention_cache + else: + curr_past_key_values = past_key_values + + current_states = key_value_states if is_cross_attention else hidden_states + if is_cross_attention and past_key_values is not None and is_updated: + # reuse k,v, cross_attentions + key_states = curr_past_key_values.layers[self.layer_idx].keys + value_states = curr_past_key_values.layers[self.layer_idx].values + else: + key_states = self.key_proj(current_states) + value_states = self.value_proj(current_states) + key_states = key_states.view(batch_size, -1, self.num_attn_heads, self.head_dim).transpose(1, 2) + value_states = value_states.view(batch_size, -1, self.num_attn_heads, self.head_dim).transpose(1, 2) + + if past_key_values is not None: + # save all key/value_states to cache to be re-used for fast auto-regressive generation + cache_position = cache_position if not is_cross_attention else None + key_states, value_states = curr_past_key_values.update( + key_states, value_states, self.layer_idx, {"cache_position": cache_position} + ) + # set flag that curr layer for cross-attn is already updated so we can re-use in subsequent calls + if is_cross_attention and isinstance(past_key_values, EncoderDecoderCache): + past_key_values.is_updated[self.layer_idx] = True + + query_states = query_states.view(batch_size, tgt_len, self.num_attn_heads, self.head_dim).transpose(1, 2) + src_len = key_states.size(2) + + attn_weights = torch.einsum("bsij,bsjk->bsik", query_states, key_states.transpose(2, 3)) + expected_shape = (batch_size, self.num_attn_heads, tgt_len, src_len) + if attn_weights.size() != expected_shape: + raise ValueError(f"Attention weights should have size {expected_shape}, but is {attn_weights.size()}") + + # This is part of a workaround to get around fork/join parallelism not supporting Optional types. + if attention_mask is not None and attention_mask.dim() == 0: + attention_mask = None + + expected_shape = (batch_size, self.num_attn_heads, 1, src_len) + if attention_mask is not None and attention_mask.size() != expected_shape: + raise ValueError(f"Attention mask should have size {expected_shape}, but is {attention_mask.size()}") + if attention_mask is not None: # don't attend to padding symbols + attn_weights = attn_weights + attention_mask + if output_attentions: + attn_weights_reshaped = attn_weights + else: + attn_weights_reshaped = None + + attn_weights = nn.functional.softmax(attn_weights, dim=-1) + + attn_probs = nn.functional.dropout( + attn_weights, + p=self.attention_dropout, + training=self.training, + ) + attn_output = torch.einsum("bsij,bsjk->bsik", attn_probs, value_states) + expected_shape = (batch_size, self.num_attn_heads, tgt_len, self.head_dim) + if attn_output.size() != expected_shape: + raise ValueError(f"`attn_output` should have shape {expected_shape}, but is of shape {attn_output.size()}") + + attn_output = attn_output.transpose(1, 2).reshape(batch_size, tgt_len, hidden_size) + attn_output = self.out_proj(attn_output) + + attn_output = nn.functional.dropout(attn_output, p=self.dropout, training=self.training) + return attn_output, attn_weights_reshaped + + +class ProphetNetFeedForward(nn.Module): + """ + This is the residual two feed-forward layer block based on the original Transformer implementation. + """ + + def __init__(self, config: ProphetNetConfig, ffn_dim: int): + super().__init__() + self.activation_fn = ACT2FN[config.activation_function] + self.intermediate = nn.Linear(config.hidden_size, ffn_dim) + self.output = nn.Linear(ffn_dim, config.hidden_size) + self.activation_dropout = config.activation_dropout + self.dropout = config.dropout + + def forward(self, hidden_states): + hidden_states = self.intermediate(hidden_states) + hidden_states = self.activation_fn(hidden_states) + + hidden_states = nn.functional.dropout(hidden_states, p=self.activation_dropout, training=self.training) + hidden_states = self.output(hidden_states) + hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training) + return hidden_states + + +class ProphetNetNgramSelfAttention(nn.Module): + def __init__(self, config: ProphetNetConfig, layer_idx=None): + super().__init__() + self.hidden_size = config.hidden_size + + self.num_buckets = config.num_buckets + self.relative_max_distance = config.relative_max_distance + self.num_attn_heads = config.num_decoder_attention_heads + self.dropout = config.dropout + self.attention_dropout = config.attention_dropout + self.head_dim = config.hidden_size // self.num_attn_heads + self.ngram = config.ngram + self.layer_idx = layer_idx + + assert self.head_dim * self.num_attn_heads == config.hidden_size, ( + "config.hidden_size must be divisible by num_attn_heads" + ) + # key, value, query projection + self.key_proj = nn.Linear(config.hidden_size, config.hidden_size) + self.value_proj = nn.Linear(config.hidden_size, config.hidden_size) + self.query_proj = nn.Linear(config.hidden_size, config.hidden_size) + + # out projection + self.out_proj = nn.Linear(config.hidden_size, config.hidden_size) + + # rel position embeddings + self.relative_pos_embeddings = nn.Linear(config.hidden_size, self.num_buckets * self.num_attn_heads) + + # for onnx runtime + self.onnx_trace = False + + def _shape(self, tensor, seq_len, batch_size): + return tensor.view(batch_size, seq_len, self.num_attn_heads, self.head_dim).transpose(1, 2).contiguous() + + def prepare_for_onnx_export_(self): + self.onnx_trace = True + + def forward( + self, + hidden_states, + past_key_values: Cache | None = None, + attention_mask=None, + extended_predict_attention_mask=None, + main_relative_position_buckets=None, + predict_relative_position_buckets=None, + position_ids=None, + cache_position=None, + ): + batch_size, ngram_sequence_length, hidden_size = hidden_states.size() + assert list(hidden_states.size()) == [batch_size, ngram_sequence_length, hidden_size], ( + f"`hidden_states` should be of shape {batch_size, ngram_sequence_length, hidden_size}, but is of shape" + f" {hidden_states.shape}" + ) + + # project + query_states = self.query_proj(hidden_states) + key_states = self.key_proj(hidden_states) + value_states = self.value_proj(hidden_states) + + # normalize + query_states = query_states / (self.head_dim**0.5) + + # reshape + query_states = self._shape(query_states, ngram_sequence_length, batch_size) + key_states = self._shape(key_states, -1, batch_size) + value_states = self._shape(value_states, -1, batch_size) + proj_shape = (batch_size, self.num_attn_heads, -1, self.head_dim) + + query_states = query_states.reshape(*proj_shape) + key_states = key_states.reshape(*proj_shape) + value_states = value_states.reshape(*proj_shape) + + # chunk into main stream and predict stream + hidden_states_list = hidden_states.chunk(1 + self.ngram, dim=1) + query_states_list = query_states.chunk(1 + self.ngram, dim=2) + key_states_list = key_states.chunk(1 + self.ngram, dim=2) + value_states_list = value_states.chunk(1 + self.ngram, dim=2) + + main_hidden_states, hidden_states_predict_list = hidden_states_list[0], hidden_states_list[1:] + main_query_states, predict_query_states_list = query_states_list[0], query_states_list[1:] + main_key_states, predict_key_states_list = key_states_list[0], key_states_list[1:] + main_value_states, predict_value_states_list = value_states_list[0], value_states_list[1:] + + # ProphetNet has two separate attention layers, one for self and one for cross attention + # We need to obtain the self attention only for this module, if `EncoderDecoderCache` + if past_key_values is not None: + if isinstance(past_key_values, EncoderDecoderCache): + curr_past_key_values = past_key_values.self_attention_cache + else: + curr_past_key_values = past_key_values + main_key_states, main_value_states = curr_past_key_values.update( + main_key_states, main_value_states, self.layer_idx, {"cache_position": cache_position} + ) + + # get seq_length of main stream only + sequence_length = ngram_sequence_length // (1 + self.ngram) + + # MAIN-STREAM + # main attn weights + # [batch_size, number_heads, sequence_length, head_dimesion] + # x [batch_size, number_heads, head_dimesion, sequence_length] + # -> [batch_size, number_heads, sequence_length, sequence_length] + main_attn_weights = torch.einsum("bntc,bncs->bnts", main_query_states, main_key_states.transpose(2, 3)) + + # retrieve relative position embeddings for each layer -> see paper for more details + main_relative_pos_embeddings = self.get_main_relative_pos_embeddings( + main_hidden_states, main_attn_weights, position_ids, main_relative_position_buckets + ) + + main_attn_weights = main_attn_weights + main_relative_pos_embeddings + + if attention_mask is not None: + main_attn_weights = main_attn_weights + attention_mask + + main_attn_probs = softmax( + main_attn_weights, + dim=-1, + onnx_trace=self.onnx_trace, + ).type_as(main_attn_weights) + + main_attn_probs = nn.functional.dropout(main_attn_probs, p=self.attention_dropout, training=self.training) + # project to attn_output + # [batch_size, number_heads, sequence_length, sequence_length] + # x [batch_size, number_heads, sequence_length, head_dimesion] + # -> [batch_size, number_heads, sequence_length, head_dimesion] + main_attn_output = torch.einsum("bntc,bncs->bnts", main_attn_probs, main_value_states) + # reshape so that num_heads dim is merged into last `head_dim` axis + main_attn_output = main_attn_output.transpose(1, 2).reshape(batch_size, 1, sequence_length, hidden_size) + main_attn_output = self.out_proj(main_attn_output) + + # PREDICT-STREAM + # [batch_size, ngram, number_heads, sequence_length, head_dimesion] + predict_query_states = torch.stack(predict_query_states_list, 1).view( + batch_size, self.ngram, self.num_attn_heads, sequence_length, self.head_dim + ) + + # [batch_size, ngram, number_heads, 2*sequence_length, head_dimesion] + predict_key_states = torch.stack([torch.cat([main_key_states, key], 2) for key in predict_key_states_list], 1) + + # [batch_size, sequence_length, ngram, hidden_size] + predict_hidden_states = torch.stack(hidden_states_predict_list, dim=2) + + # [batch_size, number_heads, ngram, 2*sequence_length, head_dimesion] + predict_value_states = torch.cat( + [torch.cat([main_value_states, v_p], 2).unsqueeze(2) for v_p in predict_value_states_list], 2 + ) + + # [batch_size, ngram, number_heads, sequence_length, head_dimesion] + # x [batch_size, ngram, number_heads, 2*sequence_length, head_dimesion] + # -> [batch_size, ngram, number_heads, sequence_length, 2*sequence_length] + predict_attn_weights = torch.einsum("bnhtc,bnhsc->bnhts", (predict_query_states, predict_key_states)) + + # retrieve relative position embeddings for each layer -> see paper for more details + # [batch_size, ngram, number_heads, sequence_length, predict_relative_pos_embeddings] + predict_relative_pos_embeddings = self.get_predict_relative_pos_embeddings( + predict_hidden_states, predict_attn_weights, position_ids, predict_relative_position_buckets + ) + + # [batch_size, ngram, number_heads, sequence_length, 2*sequence_length] + predict_attn_weights = predict_attn_weights + predict_relative_pos_embeddings + + if extended_predict_attention_mask is not None: + # Permuting Predict attention mask to [batch_size, ngram, number_heads, sequence_length, 2*sequence_length] + extended_predict_attention_mask = extended_predict_attention_mask.permute(0, 2, 1, 3, 4) + extended_predict_attention_mask = extended_predict_attention_mask.to(predict_attn_weights.dtype) + predict_attn_weights = predict_attn_weights + extended_predict_attention_mask + + predict_attn_probs = softmax( + predict_attn_weights, + dim=-1, + onnx_trace=self.onnx_trace, + ).type_as(predict_attn_weights) + + predict_attn_probs = nn.functional.dropout( + predict_attn_probs, p=self.attention_dropout, training=self.training + ) + # project to attention output + # [batch_size, ngram, number_heads, sequence_length, 2*sequence_length] + # x [batch_size, ngram, number_heads, 2*sequence_length, head_dimesion] + # -> [batch_size, ngram, number_heads, sequence_length, head_dimesion] + predict_attn_output = torch.einsum( + "bnhts,bnhsc->bnhtc", (predict_attn_probs, predict_value_states.transpose(1, 2)) + ) + + # reshape so that num_heads dim is merged into last `head_dim` axis + # [batch_size, ngram, number_heads, sequence_length, head_dimesion] -> [batch_size, ngram, sequence_length, hidden_size] + predict_attn_output = predict_attn_output.transpose(2, 3) + predict_attn_output = predict_attn_output.reshape(batch_size, self.ngram, sequence_length, hidden_size) + predict_attn_output = self.out_proj(predict_attn_output) + + # concat to single attn output + # [batch_size, (1+ngram)*sequence_length, hidden_size] + attn_output = torch.cat([main_attn_output, predict_attn_output], 1).view(batch_size, -1, hidden_size) + # reshape into better form for `config.output_attentions` + main_attn_probs = main_attn_probs.view(batch_size, self.num_attn_heads, sequence_length, -1) + + attn_output = nn.functional.dropout(attn_output, p=self.dropout, training=self.training) + + return attn_output, main_attn_probs, predict_attn_probs + + def get_main_relative_pos_embeddings( + self, hidden_states, attn_weights, position_ids, main_relative_position_buckets + ): + # input hidden_states [batch_size, sequence_length, hidden_size] + # input attn_weights [batch_size, num_heads, sequence_length, sequence_length] + # input position_ids [batch_size, sequence_length] or [1,1] + batch_size, num_attn_heads, tgt_len, src_len = attn_weights.shape + attn_weights = attn_weights.view(batch_size, num_attn_heads, tgt_len, src_len) + if main_relative_position_buckets is None: + batch_size, sequence_length = hidden_states.shape[:2] + relative_positions = ( + torch.arange(1, attn_weights.shape[-1] + 1) + .unsqueeze(0) + .unsqueeze(0) + .repeat(batch_size, sequence_length, 1) + .to(position_ids.device) + ) + # [batch_size, sequence_length, sequence_length+1] + relative_positions = relative_positions - position_ids.unsqueeze(0).repeat(batch_size, sequence_length, 1) + main_relative_position_buckets = compute_relative_buckets( + self.num_buckets, self.relative_max_distance, relative_positions, False + ) + + # [batch_size, sequence_length, num_buckets * num_heads] + rel_pos_embeddings = self.relative_pos_embeddings(hidden_states) + rel_pos_embeddings = rel_pos_embeddings.view( + rel_pos_embeddings.shape[:2] + (self.num_buckets, self.num_attn_heads) + ) + rel_pos_embeddings = rel_pos_embeddings.permute(0, 3, 1, 2) + # [batch_size, num_heads, sequence_length, num_buckets] + rel_pos_embeddings = rel_pos_embeddings.reshape(attn_weights.shape[:3] + (-1,)) + + main_relative_position_buckets = main_relative_position_buckets.repeat(1, self.num_attn_heads, 1) + # [batch_size * num_heads * sequence_length, sequence_length] + main_relative_position_buckets = main_relative_position_buckets.view( + -1, main_relative_position_buckets.shape[-1] + ) + main_relative_position_buckets = main_relative_position_buckets.long() + # [batch_size * num_heads * sequence_length, sequence_length] + rel_pos_embeddings = rel_pos_embeddings.reshape(-1, rel_pos_embeddings.size(-1)) + + main_relative_pos_embeddings = torch.gather(rel_pos_embeddings, dim=1, index=main_relative_position_buckets) + main_relative_pos_embeddings = main_relative_pos_embeddings.view(batch_size, num_attn_heads, tgt_len, -1) + return main_relative_pos_embeddings + + def get_predict_relative_pos_embeddings( + self, hidden_states, attn_weights, position_ids, predict_relative_position_buckets + ): + # input hidden_states [batch_size, sequence_length, ngram, hidden_size] + # input attn_weights [batch_size, ngram, num_heads, sequence_length, 2*sequence_length] + # input position_ids [batch_size, sequence_length] or [1,1] + # input predict_relative_position_buckets [batch_size, sequence_length, 2*sequence_length] or None + batch_size, sequence_length = hidden_states.shape[0:2] + + if predict_relative_position_buckets is None: + key_sequence_length = attn_weights.shape[-1] + assert position_ids[0][0] == key_sequence_length - 1, ( + "`position_ids` are incorrect. They should be of the format 1 2 3 4 5 ... (key_sequence_length - 1)" + ) + relative_positions = ( + torch.arange(0, key_sequence_length) + .unsqueeze(0) + .unsqueeze(0) + .repeat(batch_size, sequence_length, 1) + .to(position_ids.device) + ) + + relative_positions = relative_positions - position_ids.unsqueeze(0).repeat(batch_size, sequence_length, 1) + predict_relative_position_buckets = compute_relative_buckets( + self.num_buckets, self.relative_max_distance, relative_positions, False + ) + + # [batch_size, ngram, sequence_length, hidden_size] + hidden_states = hidden_states.transpose(1, 2) + rel_pos_embeddings = self.relative_pos_embeddings(hidden_states) + + # [batch_size, ngram, sequence_length, num_buckets, num_heads] + rel_pos_embeddings = rel_pos_embeddings.view( + hidden_states.shape[:-1] + (self.num_buckets, self.num_attn_heads) + ) + rel_pos_embeddings = rel_pos_embeddings.permute(0, 2, 1, 4, 3) + # [batch_size * ngram * sequence_length * num_heads, num_buckets] + rel_pos_embeddings = rel_pos_embeddings.reshape(-1, self.num_buckets) + # [ngram, batch_size, num_heads * sequence_length, -1] + predict_relative_position_buckets = predict_relative_position_buckets.unsqueeze(0) + predict_relative_position_buckets = predict_relative_position_buckets.repeat( + self.ngram, 1, self.num_attn_heads, 1 + ) + # [ngram * batch_size * num_heads * sequence_length, -1] + predict_relative_position_buckets = predict_relative_position_buckets.view( + -1, predict_relative_position_buckets.size(-1) + ).long() + + predict_relative_pos_embeddings = torch.gather( + rel_pos_embeddings, dim=1, index=predict_relative_position_buckets + ) + + # [batch_size, gram, num_heads, sequence_length, -1] + predict_relative_pos_embeddings = predict_relative_pos_embeddings.view( + batch_size, self.ngram, self.num_attn_heads, sequence_length, -1 + ) + + return predict_relative_pos_embeddings + + +class ProphetNetEncoderLayer(GradientCheckpointingLayer): + """ + Encoder block for Prophetnet + """ + + def __init__(self, config: ProphetNetConfig): + super().__init__() + # 1st residual block + self.self_attn = ProphetNetAttention(config, config.num_encoder_attention_heads) + self.self_attn_layer_norm = LayerNorm(config.hidden_size) + + # 2nd residual block + self.feed_forward = ProphetNetFeedForward(config, config.encoder_ffn_dim) + self.feed_forward_layer_norm = LayerNorm(config.hidden_size) + + def forward( + self, + hidden_states, + attention_mask, + output_attentions: bool = False, + ): + # 1st residual block + attention_output, attn_weights = self.self_attn( + hidden_states=hidden_states, + attention_mask=attention_mask, + output_attentions=output_attentions, + ) + hidden_states = self.self_attn_layer_norm(attention_output + hidden_states) + + # 2nd residual block + feed_forward_output = self.feed_forward(hidden_states) + hidden_states = self.feed_forward_layer_norm(feed_forward_output + hidden_states) + + outputs = (hidden_states,) + + if output_attentions: + outputs += (attn_weights,) + + return outputs + + +class ProphetNetDecoderLayer(GradientCheckpointingLayer): + """ + Decoder block for Prophetnet + """ + + def __init__(self, config: ProphetNetConfig, layer_idx=None): + super().__init__() + # 1st residual block + self.self_attn = ProphetNetNgramSelfAttention(config, layer_idx=layer_idx) + self.self_attn_layer_norm = LayerNorm(config.hidden_size) + + # 2nd residual block + if config.add_cross_attention: + self.cross_attn = ProphetNetAttention(config, config.num_decoder_attention_heads, layer_idx=layer_idx) + self.cross_attn_layer_norm = LayerNorm(config.hidden_size) + + # 3rd residual block + self.feed_forward = ProphetNetFeedForward(config, config.decoder_ffn_dim) + self.feed_forward_layer_norm = LayerNorm(config.hidden_size) + + def forward( + self, + hidden_states, + attention_mask=None, + encoder_hidden_states=None, + encoder_attn_mask=None, + extended_predict_attention_mask=None, + main_relative_position_buckets=None, + predict_relative_position_buckets=None, + position_ids=None, + past_key_values=None, + use_cache: bool | None = True, + output_attentions: bool | None = False, + cache_position: torch.Tensor | None = None, + ): + # 1st residual block + ngram_attention_output, self_attn_weights, self_attn_weights_ngram = self.self_attn( + hidden_states=hidden_states, + past_key_values=past_key_values, + attention_mask=attention_mask, + extended_predict_attention_mask=extended_predict_attention_mask, + main_relative_position_buckets=main_relative_position_buckets, + predict_relative_position_buckets=predict_relative_position_buckets, + position_ids=position_ids, + ) + hidden_states = self.self_attn_layer_norm(hidden_states + ngram_attention_output) + + cross_attn_weights = None + if encoder_hidden_states is not None: + # 2nd residual block + attention_output, cross_attn_weights = self.cross_attn( + hidden_states=hidden_states, + key_value_states=encoder_hidden_states, + attention_mask=encoder_attn_mask, + past_key_values=past_key_values, + output_attentions=output_attentions, + ) + hidden_states = self.cross_attn_layer_norm(attention_output + hidden_states) + + # 3rd residual block + feed_forward_output = self.feed_forward(hidden_states) + hidden_states = self.feed_forward_layer_norm(feed_forward_output + hidden_states) + + outputs = (hidden_states,) + + if output_attentions: + outputs += (self_attn_weights, self_attn_weights_ngram, cross_attn_weights) + + return outputs + + +@auto_docstring( + custom_intro=""" + The standalone encoder part of the ProphetNetModel. + """ +) +class ProphetNetEncoder(ProphetNetPreTrainedModel): + def __init__(self, config: ProphetNetConfig): + super().__init__(config) + + self.word_embeddings = nn.Embedding(config.vocab_size, config.hidden_size, padding_idx=config.pad_token_id) + self.position_embeddings = ProphetNetPositionalEmbeddings(config) + self.embeddings_layer_norm = LayerNorm(config.hidden_size) + + self.layers = nn.ModuleList([ProphetNetEncoderLayer(config) for _ in range(config.num_encoder_layers)]) + + self.gradient_checkpointing = False + # Initialize weights and apply final processing + self.post_init() + + def get_input_embeddings(self): + return self.word_embeddings + + def set_input_embeddings(self, value): + self.word_embeddings = value + + @auto_docstring + def forward( + self, + input_ids: torch.Tensor | None = None, + attention_mask: torch.Tensor | None = None, + inputs_embeds: torch.Tensor | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + **kwargs, + ) -> tuple | BaseModelOutput: + r""" + Example: + + ```python + >>> from transformers import AutoTokenizer, ProphetNetEncoder + >>> import torch + + >>> tokenizer = AutoTokenizer.from_pretrained("microsoft/prophetnet-large-uncased") + >>> model = ProphetNetEncoder.from_pretrained("patrickvonplaten/prophetnet-large-uncased-standalone") + >>> inputs = tokenizer("Hello, my dog is cute", return_tensors="pt") + >>> outputs = model(**inputs) + + >>> last_hidden_states = outputs.last_hidden_state + ```""" + + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + if input_ids is None and inputs_embeds is None: + raise ValueError("Either input_ids or inputs_embeds has to be passed.") + elif input_ids is not None and inputs_embeds is not None: + raise ValueError("Make sure to only pass input_ids or inputs_embeds.") + elif input_ids is not None and inputs_embeds is None: + inputs_embeds = self.word_embeddings(input_ids) + + # prepare attention mask + if attention_mask is not None: + extended_attention_mask = ( + 1.0 - attention_mask[:, None, None, :].repeat(1, self.config.num_encoder_attention_heads, 1, 1) + ) * torch.finfo(self.dtype).min + extended_attention_mask = extended_attention_mask.to(inputs_embeds.dtype) + else: + extended_attention_mask = None + + position_embeddings, position_ids = self.position_embeddings(inputs_embeds.shape[:2], inputs_embeds.device) + + hidden_states = inputs_embeds + position_embeddings + hidden_states = self.embeddings_layer_norm(hidden_states) + hidden_states = nn.functional.dropout(hidden_states, p=self.config.dropout, training=self.training) + + encoder_hidden_states = () if output_hidden_states else None + all_attentions = () if output_attentions else None + + for idx, encoder_layer in enumerate(self.layers): + if output_hidden_states: + encoder_hidden_states = encoder_hidden_states + (hidden_states,) + + layer_outputs = encoder_layer( + hidden_states, + attention_mask=extended_attention_mask, + output_attentions=output_attentions, + ) + + hidden_states = layer_outputs[0] + + if output_attentions: + all_attentions = all_attentions + (layer_outputs[1],) + + if output_hidden_states: + encoder_hidden_states = encoder_hidden_states + (hidden_states,) + + if not return_dict: + return tuple(v for v in [hidden_states, encoder_hidden_states, all_attentions] if v is not None) + return BaseModelOutput( + last_hidden_state=hidden_states, hidden_states=encoder_hidden_states, attentions=all_attentions + ) + + +@auto_docstring( + custom_intro=""" + The standalone decoder part of the ProphetNetModel. + """ +) +class ProphetNetDecoder(ProphetNetPreTrainedModel): + def __init__(self, config: ProphetNetConfig): + super().__init__(config) + + self.ngram = config.ngram + self.num_buckets = config.num_buckets + self.relative_max_distance = config.relative_max_distance + self.dropout = config.dropout + self.max_target_positions = config.max_position_embeddings + + self.word_embeddings = nn.Embedding(config.vocab_size, config.hidden_size, padding_idx=config.pad_token_id) + self.position_embeddings = ProphetNetPositionalEmbeddings(config) + + self.ngram_embeddings = nn.Embedding(self.ngram, config.hidden_size, None) + self.layers = nn.ModuleList( + [ProphetNetDecoderLayer(config, layer_idx=i) for i in range(config.num_decoder_layers)] + ) + self.embeddings_layer_norm = LayerNorm(config.hidden_size) + + self.gradient_checkpointing = False + # Initialize weights and apply final processing + self.post_init() + + def get_input_embeddings(self): + return self.word_embeddings + + def set_input_embeddings(self, value): + self.word_embeddings = value + + @auto_docstring + def forward( + self, + input_ids: torch.Tensor | None = None, + attention_mask: torch.Tensor | None = None, + encoder_hidden_states: torch.Tensor | None = None, + encoder_attention_mask: torch.Tensor | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.Tensor | None = None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + cache_position: torch.Tensor | None = None, + **kwargs, + ) -> tuple | ProphetNetDecoderModelOutput: + r""" + Example: + + ```python + >>> from transformers import AutoTokenizer, ProphetNetDecoder + >>> import torch + + >>> tokenizer = AutoTokenizer.from_pretrained("microsoft/prophetnet-large-uncased") + >>> model = ProphetNetDecoder.from_pretrained("microsoft/prophetnet-large-uncased", add_cross_attention=False) + >>> inputs = tokenizer("Hello, my dog is cute", return_tensors="pt") + >>> outputs = model(**inputs) + + >>> last_hidden_states = outputs.last_hidden_state + ```""" + use_cache = use_cache if use_cache is not None else self.config.use_cache + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + if input_ids is None and inputs_embeds is None: + raise ValueError("Either `decoder_input_ids` or `decoder_inputs_embeds` has to be passed.") + elif input_ids is not None and inputs_embeds is not None: + raise ValueError("Make sure to only pass `decoder_input_ids` or `decoder_inputs_embeds`.") + elif input_ids is not None and inputs_embeds is None: + inputs_embeds = self.word_embeddings(input_ids) + + batch_size, sequence_length = inputs_embeds.shape[:2] + + if self.gradient_checkpointing and self.training: + if use_cache: + logger.warning_once( + "`use_cache=True` is incompatible with gradient checkpointing. Setting `use_cache=False`..." + ) + use_cache = False + + if use_cache and past_key_values is None: + past_key_values = ( + EncoderDecoderCache(DynamicCache(config=self.config), DynamicCache(config=self.config)) + if encoder_hidden_states is not None or self.config.is_encoder_decoder + else DynamicCache(config=self.config) + ) + + past_key_values_length = past_key_values.get_seq_length() if past_key_values is not None else 0 + + main_stream_pos_embed, position_ids = self.position_embeddings( + (batch_size, sequence_length), + device=inputs_embeds.device, + past_key_values=past_key_values, + ) + + if past_key_values_length != 0: + main_relative_position_buckets, predict_relative_position_buckets = None, None + else: + ( + main_relative_position_buckets, + predict_relative_position_buckets, + ) = self.compute_buffered_relative_buckets(position_ids) + predicting_stream_pos_embed = self.position_embeddings._forward(position_ids + 1) + + # add position embeddings + hidden_states = inputs_embeds + main_stream_pos_embed + + ngram_embeddings = self.ngram_embeddings.weight + + # prepare attention mask + if past_key_values_length != 0: + assert hidden_states.size(1) == 1, ( + "At the moment `use_cache` is only supported for `decoder_input_ids` of length 1" + ) + + ngram_hidden_states = [ + (ngram_embeddings[ngram - 1] + predicting_stream_pos_embed).repeat(batch_size, 1, 1) + for ngram in range(self.ngram) + ] + extended_attention_mask = None + extended_predict_attention_mask = None + else: + ngram_hidden_states = [ + (ngram_embeddings[ngram - 1] + predicting_stream_pos_embed) for ngram in range(self.ngram) + ] + extended_attention_mask = self.prepare_attention_mask(hidden_states, attention_mask) + extended_predict_attention_mask = self.prepare_predict_attention_mask(hidden_states, attention_mask) + + # prepare encoder attention mask + if encoder_attention_mask is not None: + extended_encoder_attention_mask = ( + 1.0 - encoder_attention_mask[:, None, None, :].repeat(1, self.config.num_decoder_attention_heads, 1, 1) + ) * torch.finfo(self.dtype).min + extended_encoder_attention_mask = extended_encoder_attention_mask.to(inputs_embeds.dtype) + else: + extended_encoder_attention_mask = None + + hidden_states = torch.cat([hidden_states] + ngram_hidden_states, 1) + + if self.embeddings_layer_norm: + hidden_states = self.embeddings_layer_norm(hidden_states) + + hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training) + + # init attentions, hidden_states and cache with empty tuples + all_main_stream_hidden_states = () if output_hidden_states else None + all_ngram_stream_hidden_states = () if output_hidden_states and self.config.ngram > 0 else None + + all_main_stream_attns = () if output_attentions else None + all_ngram_stream_attns = () if output_attentions else None + all_cross_attns = () if output_attentions and self.config.add_cross_attention else None + + for idx, decoder_layer in enumerate(self.layers): + if output_hidden_states: + # grad cannot be kept because tensor is sliced + all_main_stream_hidden_states += (hidden_states[:, :sequence_length],) + if self.config.ngram > 0: + all_ngram_stream_hidden_states += (hidden_states[:, sequence_length:],) + + layer_outputs = decoder_layer( + hidden_states, + extended_attention_mask, + encoder_hidden_states, # as a positional argument for gradient checkpointing + encoder_attn_mask=extended_encoder_attention_mask, + extended_predict_attention_mask=extended_predict_attention_mask, + main_relative_position_buckets=main_relative_position_buckets, + predict_relative_position_buckets=predict_relative_position_buckets, + position_ids=position_ids, + past_key_values=past_key_values, + use_cache=use_cache, + output_attentions=output_attentions, + cache_position=cache_position, + ) + + hidden_states = layer_outputs[0] + if output_attentions: + all_main_stream_attns += (layer_outputs[1],) + all_ngram_stream_attns += (layer_outputs[2],) + + if self.config.add_cross_attention: + all_cross_attns += (layer_outputs[3],) + + if output_hidden_states: + all_main_stream_hidden_states += (hidden_states[:, :sequence_length],) + if self.config.ngram > 0: + all_ngram_stream_hidden_states += (hidden_states[:, sequence_length:],) + + # split last_hidden_state for return + last_hidden_state = hidden_states[:, :sequence_length] + last_hidden_state_ngram = hidden_states[:, sequence_length:] if self.config.ngram > 0 else None + + if not return_dict: + return tuple( + v + for v in [ + last_hidden_state, + last_hidden_state_ngram, + past_key_values, + all_main_stream_hidden_states, + all_ngram_stream_hidden_states, + all_main_stream_attns, + all_ngram_stream_attns, + all_cross_attns, + ] + if v is not None + ) + return ProphetNetDecoderModelOutput( + last_hidden_state=last_hidden_state, + last_hidden_state_ngram=last_hidden_state_ngram, + past_key_values=past_key_values, + hidden_states=all_main_stream_hidden_states, + hidden_states_ngram=all_ngram_stream_hidden_states, + attentions=all_main_stream_attns, + ngram_attentions=all_ngram_stream_attns, + cross_attentions=all_cross_attns, + ) + + def compute_buffered_relative_buckets(self, position_ids): + batch_size, sequence_length = position_ids.shape + + position_ids = torch.arange(1, self.max_target_positions).to(position_ids.device).repeat(1, 1) + main_relative_buckets, predict_relative_buckets = compute_all_stream_relative_buckets( + self.num_buckets, self.relative_max_distance, position_ids + ) + + # buffer relative buckets + main_relative_buckets = main_relative_buckets[:, :sequence_length, :sequence_length].repeat(batch_size, 1, 1) + predict_relative_buckets = torch.cat( + [ + predict_relative_buckets[:, :sequence_length, :sequence_length], + predict_relative_buckets[ + :, :sequence_length, self.max_target_positions : self.max_target_positions + sequence_length + ], + ], + 2, + ).repeat(batch_size, 1, 1) + + return main_relative_buckets, predict_relative_buckets + + def prepare_attention_mask(self, hidden_states, attention_mask): + batch_size, seq_length = hidden_states.shape[:2] + + # get causal mask + causal_mask = torch.full( + (seq_length, seq_length), + torch.finfo(hidden_states.dtype).min, + dtype=hidden_states.dtype, + device=hidden_states.device, + ) + causal_mask = torch.triu(causal_mask, 1) + + extended_causal_mask = causal_mask[:seq_length, :seq_length][None, None, :, :].expand( + (batch_size, self.config.num_decoder_attention_heads) + causal_mask.shape + ) + + # add usual attention mask + if attention_mask is not None: + extended_attention_mask = (1.0 - attention_mask[:, None, None, :]) * torch.finfo(self.dtype).min + extended_attention_mask = extended_causal_mask + extended_attention_mask + else: + extended_attention_mask = extended_causal_mask + return extended_attention_mask.to(hidden_states.dtype) + + def prepare_predict_attention_mask(self, hidden_states, attention_mask): + batch_size, seq_length = hidden_states.shape[:2] + + # get causal mask + predict_causal_mask = ngram_attention_bias( + self.max_target_positions, self.ngram, hidden_states.device, hidden_states.dtype + ) + predict_causal_mask = torch.cat( + [ + predict_causal_mask[:, :seq_length, :seq_length], + predict_causal_mask[ + :, :seq_length, self.max_target_positions : self.max_target_positions + seq_length + ], + ], + dim=-1, + ) + extended_predict_causal_mask = predict_causal_mask[None, None, :, :, :].expand( + (batch_size, self.config.num_decoder_attention_heads) + predict_causal_mask.shape + ) + + # add usual attention mask + if attention_mask is not None: + extended_attention_mask = (1.0 - attention_mask[:, None, None, None, :]) * torch.finfo(self.dtype).min + extended_attention_mask = extended_attention_mask.expand( + (batch_size, self.config.num_decoder_attention_heads, self.ngram, seq_length, seq_length) + ) + # predicted stream attention_mask should always be 0 + extended_attention_mask = torch.cat( + [extended_attention_mask, torch.zeros_like(extended_attention_mask)], dim=-1 + ) + extended_predict_attention_mask = extended_predict_causal_mask + extended_attention_mask + else: + extended_predict_attention_mask = extended_predict_causal_mask + return extended_predict_attention_mask.to(hidden_states.dtype) + + +@auto_docstring +class ProphetNetModel(ProphetNetPreTrainedModel): + _tied_weights_keys = { + "encoder.word_embeddings.weight": "word_embeddings.weight", + "decoder.word_embeddings.weight": "word_embeddings.weight", + } + + def __init__(self, config: ProphetNetConfig): + super().__init__(config) + self.word_embeddings = nn.Embedding(config.vocab_size, config.hidden_size, padding_idx=config.pad_token_id) + + encoder_config = copy.deepcopy(config) + encoder_config.use_cache = False + self.encoder = ProphetNetEncoder(encoder_config) + + decoder_config = copy.deepcopy(config) + decoder_config.is_decoder = True + self.decoder = ProphetNetDecoder(decoder_config) + + # Initialize weights and apply final processing + self.post_init() + + def get_input_embeddings(self): + return self.word_embeddings + + def set_input_embeddings(self, value): + self.word_embeddings = value + self.encoder.word_embeddings = self.word_embeddings + self.decoder.word_embeddings = self.word_embeddings + + @auto_docstring + def forward( + self, + input_ids: torch.Tensor | None = None, + attention_mask: torch.Tensor | None = None, + decoder_input_ids: torch.Tensor | None = None, + decoder_attention_mask: torch.BoolTensor | None = None, + encoder_outputs: tuple | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.Tensor | None = None, + decoder_inputs_embeds: torch.Tensor | None = None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + cache_position: torch.Tensor | None = None, + **kwargs, + ) -> tuple | ProphetNetSeq2SeqModelOutput: + r""" + decoder_input_ids (`torch.LongTensor` of shape `(batch_size, target_sequence_length)`, *optional*): + Indices of decoder input sequence tokens in the vocabulary. + + Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and + [`PreTrainedTokenizer.__call__`] for details. + + [What are decoder input IDs?](../glossary#decoder-input-ids) + + ProphetNet uses the `eos_token_id` as the starting token for `decoder_input_ids` generation. If + `past_key_values` is used, optionally only the last `decoder_input_ids` have to be input (see + `past_key_values`). + decoder_attention_mask (`torch.BoolTensor` of shape `(batch_size, target_sequence_length)`, *optional*): + Default behavior: generate a tensor that ignores pad tokens in `decoder_input_ids`. Causal mask will also + be used by default. + + Example: + + ```python + >>> from transformers import AutoTokenizer, ProphetNetModel + + >>> tokenizer = AutoTokenizer.from_pretrained("microsoft/prophetnet-large-uncased") + >>> model = ProphetNetModel.from_pretrained("microsoft/prophetnet-large-uncased") + + >>> input_ids = tokenizer( + ... "Studies have been shown that owning a dog is good for you", return_tensors="pt" + ... ).input_ids # Batch size 1 + >>> decoder_input_ids = tokenizer("Studies show that", return_tensors="pt").input_ids # Batch size 1 + >>> outputs = model(input_ids=input_ids, decoder_input_ids=decoder_input_ids) + + >>> last_hidden_states = outputs.last_hidden_state # main stream hidden states + >>> last_hidden_states_ngram = outputs.last_hidden_state_ngram # predict hidden states + ```""" + use_cache = use_cache if use_cache is not None else self.config.use_cache + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + if encoder_outputs is None: + encoder_outputs = self.encoder( + input_ids=input_ids, + attention_mask=attention_mask, + inputs_embeds=inputs_embeds, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + + # decoder outputs consists of (dec_features, past_key_values, dec_hidden, dec_attn) + decoder_outputs = self.decoder( + input_ids=decoder_input_ids, + attention_mask=decoder_attention_mask, + encoder_hidden_states=encoder_outputs[0], + encoder_attention_mask=attention_mask, + past_key_values=past_key_values, + inputs_embeds=decoder_inputs_embeds, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + use_cache=use_cache, + return_dict=return_dict, + cache_position=cache_position, + ) + + if not return_dict: + return decoder_outputs + encoder_outputs + return ProphetNetSeq2SeqModelOutput( + last_hidden_state=decoder_outputs.last_hidden_state, + last_hidden_state_ngram=decoder_outputs.last_hidden_state_ngram, + past_key_values=decoder_outputs.past_key_values, + decoder_hidden_states=decoder_outputs.hidden_states, + decoder_ngram_hidden_states=decoder_outputs.hidden_states_ngram, + decoder_attentions=decoder_outputs.attentions, + decoder_ngram_attentions=decoder_outputs.ngram_attentions, + cross_attentions=decoder_outputs.cross_attentions, + encoder_last_hidden_state=encoder_outputs.last_hidden_state, + encoder_hidden_states=encoder_outputs.hidden_states, + encoder_attentions=encoder_outputs.attentions, + ) + + +@auto_docstring( + custom_intro=""" + The ProphetNet Model with a language modeling head. Can be used for sequence generation tasks. + """ +) +class ProphetNetForConditionalGeneration(ProphetNetPreTrainedModel, GenerationMixin): + _tied_weights_keys = { + "lm_head.weight": "prophetnet.word_embeddings.weight", + } + + def __init__(self, config: ProphetNetConfig): + super().__init__(config) + self.prophetnet = ProphetNetModel(config) + self.padding_idx = config.pad_token_id + self.disable_ngram_loss = config.disable_ngram_loss + + self.lm_head = nn.Linear(config.hidden_size, config.vocab_size, bias=False) + + # Initialize weights and apply final processing + self.post_init() + + def get_input_embeddings(self): + return self.prophetnet.word_embeddings + + @auto_docstring + def forward( + self, + input_ids: torch.Tensor | None = None, + attention_mask: torch.Tensor | None = None, + decoder_input_ids: torch.Tensor | None = None, + decoder_attention_mask: torch.BoolTensor | None = None, + encoder_outputs: torch.Tensor | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.Tensor | None = None, + decoder_inputs_embeds: torch.Tensor | None = None, + labels: torch.Tensor | None = None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + cache_position: torch.Tensor | None = None, + **kwargs, + ) -> tuple | ProphetNetSeq2SeqLMOutput: + r""" + decoder_input_ids (`torch.LongTensor` of shape `(batch_size, target_sequence_length)`, *optional*): + Indices of decoder input sequence tokens in the vocabulary. + + Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and + [`PreTrainedTokenizer.__call__`] for details. + + [What are decoder input IDs?](../glossary#decoder-input-ids) + + ProphetNet uses the `eos_token_id` as the starting token for `decoder_input_ids` generation. If + `past_key_values` is used, optionally only the last `decoder_input_ids` have to be input (see + `past_key_values`). + decoder_attention_mask (`torch.BoolTensor` of shape `(batch_size, target_sequence_length)`, *optional*): + Default behavior: generate a tensor that ignores pad tokens in `decoder_input_ids`. Causal mask will also + be used by default. + labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*): + Labels for computing the sequence classification/regression loss. Indices should be in `[-100, 0, ..., + config.vocab_size - 1]`. All labels set to `-100` are ignored (masked), the loss is only computed for + labels in `[0, ..., config.vocab_size]` + + Example: + + ```python + >>> from transformers import AutoTokenizer, ProphetNetForConditionalGeneration + + >>> tokenizer = AutoTokenizer.from_pretrained("microsoft/prophetnet-large-uncased") + >>> model = ProphetNetForConditionalGeneration.from_pretrained("microsoft/prophetnet-large-uncased") + + >>> input_ids = tokenizer( + ... "Studies have been shown that owning a dog is good for you", return_tensors="pt" + ... ).input_ids # Batch size 1 + >>> decoder_input_ids = tokenizer("Studies show that", return_tensors="pt").input_ids # Batch size 1 + >>> outputs = model(input_ids=input_ids, decoder_input_ids=decoder_input_ids) + + >>> logits_next_token = outputs.logits # logits to predict next token as usual + >>> logits_ngram_next_tokens = outputs.logits_ngram # logits to predict 2nd, 3rd, ... next tokens + ```""" + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + if labels is not None and decoder_input_ids is None and decoder_inputs_embeds is None: + # get decoder inputs from shifting lm labels to the right + decoder_input_ids = self._shift_right(labels) + + outputs = self.prophetnet( + input_ids=input_ids, + attention_mask=attention_mask, + decoder_input_ids=decoder_input_ids, + decoder_attention_mask=decoder_attention_mask, + encoder_outputs=encoder_outputs, + past_key_values=past_key_values, + inputs_embeds=inputs_embeds, + decoder_inputs_embeds=decoder_inputs_embeds, + use_cache=use_cache, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + cache_position=cache_position, + ) + batch_size, sequence_length = ( + decoder_input_ids.shape if decoder_input_ids is not None else decoder_inputs_embeds.shape[:2] + ) + + predicting_streams = outputs[1].view(batch_size, self.config.ngram, sequence_length, -1) + predict_logits = self.lm_head(predicting_streams) + + logits = predict_logits[:, 0] + logits_ngram = predict_logits[:, 1:] if self.config.ngram > 1 else None + + # To use .view in loss computation, make sure that logits is contiguous. + if not logits.is_contiguous(): + logits = logits.contiguous() + + loss = None + if labels is not None: + loss = self._compute_loss(predict_logits, labels) + + if not return_dict: + all_logits = tuple(v for v in [logits, logits_ngram] if v is not None) + return (loss,) + all_logits + outputs[2:] if loss is not None else all_logits + outputs[2:] + else: + return ProphetNetSeq2SeqLMOutput( + loss=loss, + logits=logits, + logits_ngram=logits_ngram, + past_key_values=outputs.past_key_values, + decoder_hidden_states=outputs.decoder_hidden_states, + decoder_ngram_hidden_states=outputs.decoder_ngram_hidden_states, + decoder_attentions=outputs.decoder_attentions, + decoder_ngram_attentions=outputs.decoder_ngram_attentions, + cross_attentions=outputs.cross_attentions, + encoder_last_hidden_state=outputs.encoder_last_hidden_state, + encoder_hidden_states=outputs.encoder_hidden_states, + encoder_attentions=outputs.encoder_attentions, + ) + + def _compute_loss(self, logits, labels, ignore_index=-100): + expend_targets = labels.new_zeros(self.config.ngram, labels.size(0), labels.size(1)).fill_(ignore_index) + + for i in range(self.config.ngram): + if i > 0 and self.disable_ngram_loss: + break + expend_targets[i, :, :] = labels + + logits = logits.transpose(0, 1).contiguous() + lprobs = nn.functional.log_softmax( + logits.view(-1, logits.size(-1)), + dim=-1, + dtype=torch.float32, + ) + + loss = nn.functional.nll_loss(lprobs, expend_targets.view(-1), reduction="mean") + + if self.config.eps > 0.0: + smooth_loss = -lprobs.sum(dim=-1, keepdim=True) + non_masked_tokens = expend_targets.ne(ignore_index).view(-1) + smooth_loss = smooth_loss[non_masked_tokens] + smooth_loss = smooth_loss.mean() + + eps_i = self.config.eps / lprobs.size(-1) + loss = (1.0 - self.config.eps) * loss + eps_i * smooth_loss + + return loss + + def prepare_decoder_input_ids_from_labels(self, labels: torch.Tensor): + return self._shift_right(labels) + + def get_encoder(self, modality=None): + if modality is None: + return self.prophetnet.encoder + else: + return super().get_encoder(modality=modality) + + +@auto_docstring( + custom_intro=""" + The standalone decoder part of the ProphetNetModel with a lm head on top. The model can be used for causal + """ +) +class ProphetNetForCausalLM(ProphetNetPreTrainedModel, GenerationMixin): + _tied_weights_keys = { + "lm_head.weight": "prophetnet.word_embeddings.weight", + "prophetnet.decoder.word_embeddings.weight": "prophetnet.word_embeddings.weight", + } + + def __init__(self, config: ProphetNetConfig): + # set config for CLM + config = copy.deepcopy(config) + config.is_decoder = True + config.is_encoder_decoder = False + super().__init__(config) + self.prophetnet = ProphetNetDecoderWrapper(config) + + self.padding_idx = config.pad_token_id + self.disable_ngram_loss = config.disable_ngram_loss + + self.lm_head = nn.Linear(config.hidden_size, config.vocab_size, bias=False) + + # Initialize weights and apply final processing + self.post_init() + + def get_input_embeddings(self): + return self.prophetnet.decoder.word_embeddings + + def set_input_embeddings(self, value): + self.prophetnet.decoder.word_embeddings = value + + @auto_docstring + def forward( + self, + input_ids: torch.Tensor | None = None, + attention_mask: torch.Tensor | None = None, + encoder_hidden_states: torch.Tensor | None = None, + encoder_attention_mask: torch.Tensor | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.Tensor | None = None, + labels: torch.Tensor | None = None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + **kwargs, + ) -> tuple | ProphetNetDecoderLMOutput: + r""" + labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Labels for computing the left-to-right language modeling loss (next word prediction). Indices should be in + `[-100, 0, ..., config.vocab_size]` (see `input_ids` docstring) Tokens with indices set to `-100` are + ignored (masked), the loss is only computed for the tokens with labels n `[0, ..., config.vocab_size]` + + Example: + + ```python + >>> from transformers import AutoTokenizer, ProphetNetForCausalLM + >>> import torch + + >>> tokenizer = AutoTokenizer.from_pretrained("microsoft/prophetnet-large-uncased") + >>> model = ProphetNetForCausalLM.from_pretrained("microsoft/prophetnet-large-uncased") + >>> assert model.config.is_decoder, f"{model.__class__} has to be configured as a decoder." + >>> inputs = tokenizer("Hello, my dog is cute", return_tensors="pt") + >>> outputs = model(**inputs) + + >>> logits = outputs.logits + + >>> # Model can also be used with EncoderDecoder framework + >>> from transformers import BertTokenizer, EncoderDecoderModel, AutoTokenizer + >>> import torch + + >>> tokenizer_enc = BertTokenizer.from_pretrained("google-bert/bert-large-uncased") + >>> tokenizer_dec = AutoTokenizer.from_pretrained("microsoft/prophetnet-large-uncased") + >>> model = EncoderDecoderModel.from_encoder_decoder_pretrained( + ... "google-bert/bert-large-uncased", "microsoft/prophetnet-large-uncased" + ... ) + + >>> ARTICLE = ( + ... "the us state department said wednesday it had received no " + ... "formal word from bolivia that it was expelling the us ambassador there " + ... "but said the charges made against him are `` baseless ." + ... ) + >>> input_ids = tokenizer_enc(ARTICLE, return_tensors="pt").input_ids + >>> labels = tokenizer_dec( + ... "us rejects charges against its ambassador in bolivia", return_tensors="pt" + ... ).input_ids + >>> outputs = model(input_ids=input_ids, decoder_input_ids=labels[:, :-1], labels=labels[:, 1:]) + + >>> loss = outputs.loss + ```""" + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + # decoder outputs consists of (dec_features, past_key_values, dec_hidden, dec_attn) + outputs = self.prophetnet.decoder( + input_ids=input_ids, + attention_mask=attention_mask, + encoder_hidden_states=encoder_hidden_states, + encoder_attention_mask=encoder_attention_mask, + past_key_values=past_key_values, + inputs_embeds=inputs_embeds, + use_cache=use_cache, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + + batch_size, sequence_length = input_ids.shape if input_ids is not None else inputs_embeds.shape[:2] + + predicting_streams = outputs[1].view(batch_size, self.config.ngram, sequence_length, -1) + predict_logits = self.lm_head(predicting_streams) + + logits = predict_logits[:, 0] + logits_ngram = predict_logits[:, 1:] if self.config.ngram > 1 else None + + loss = None + if labels is not None: + loss = self._compute_loss(predict_logits, labels) + + if not return_dict: + all_logits = tuple(v for v in [logits, logits_ngram] if v is not None) + return (loss,) + all_logits + outputs[2:] if loss is not None else all_logits + outputs[2:] + else: + return ProphetNetDecoderLMOutput( + loss=loss, + logits=logits, + logits_ngram=logits_ngram, + past_key_values=outputs.past_key_values, + hidden_states=outputs.hidden_states, + hidden_states_ngram=outputs.hidden_states_ngram, + attentions=outputs.attentions, + ngram_attentions=outputs.ngram_attentions, + cross_attentions=outputs.cross_attentions, + ) + + def _compute_loss(self, logits, labels, ignore_index=-100): + expend_targets = labels.new_zeros(self.config.ngram, labels.size(0), labels.size(1)).fill_(ignore_index) + + for i in range(self.config.ngram): + if i > 0 and self.disable_ngram_loss: + break + expend_targets[i, :, :] = labels + + logits = logits.transpose(0, 1).contiguous() + lprobs = nn.functional.log_softmax( + logits.view(-1, logits.size(-1)), + dim=-1, + dtype=torch.float32, + ) + + loss = nn.functional.nll_loss(lprobs, expend_targets.view(-1), reduction="mean") + + if self.config.eps > 0.0: + smooth_loss = -lprobs.sum(dim=-1, keepdim=True) + non_masked_tokens = expend_targets.ne(ignore_index).view(-1) + smooth_loss = smooth_loss[non_masked_tokens] + smooth_loss = smooth_loss.mean() + + eps_i = self.config.eps / lprobs.size(-1) + loss = (1.0 - self.config.eps) * loss + eps_i * smooth_loss + + return loss + + def prepare_inputs_for_generation( + self, + input_ids, + past_key_values=None, + attention_mask=None, + use_cache=None, + is_first_iteration=False, + **kwargs, + ): + # Overwritten -- Prophetnet does not support cache_position + + model_inputs = super().prepare_inputs_for_generation( + input_ids, + past_key_values=past_key_values, + attention_mask=attention_mask, + use_cache=use_cache, + is_first_iteration=is_first_iteration, + **kwargs, + ) + + model_inputs.pop("cache_position", None) + + return model_inputs + + +class ProphetNetDecoderWrapper(ProphetNetPreTrainedModel): + """ + This is a wrapper class, so that [`ProphetNetForCausalLM`] can correctly be loaded from pretrained prophetnet + classes. + """ + + _tied_weights_keys = { + "decoder.word_embeddings.weight": "word_embeddings.weight", + } + + def __init__(self, config: ProphetNetConfig): + super().__init__(config) + + self.word_embeddings = nn.Embedding(config.vocab_size, config.hidden_size, padding_idx=config.pad_token_id) + self.decoder = ProphetNetDecoder(config) + + # Initialize weights and apply final processing + self.post_init() + + def forward(self, *args, **kwargs): + return self.decoder(*args, **kwargs) + + +__all__ = [ + "ProphetNetDecoder", + "ProphetNetEncoder", + "ProphetNetForCausalLM", + "ProphetNetForConditionalGeneration", + "ProphetNetModel", + "ProphetNetPreTrainedModel", +] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/prophetnet/tokenization_prophetnet.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/prophetnet/tokenization_prophetnet.py new file mode 100644 index 0000000000000000000000000000000000000000..b19c414e72d11e3b54b248fc2be7d16093eb419d --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/prophetnet/tokenization_prophetnet.py @@ -0,0 +1,475 @@ +# Copyright 2020 The Microsoft Authors and The HuggingFace Inc. team. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import collections +import os +import unicodedata +from collections.abc import Iterable + +from ...tokenization_python import PreTrainedTokenizer, _is_control, _is_punctuation, _is_whitespace +from ...utils import logging + + +logger = logging.get_logger(__name__) + +VOCAB_FILES_NAMES = {"vocab_file": "prophetnet.tokenizer"} + + +def whitespace_tokenize(text): + """Runs basic whitespace cleaning and splitting on a piece of text.""" + text = text.strip() + if not text: + return [] + tokens = text.split() + return tokens + + +class BasicTokenizer: + """ + Constructs a BasicTokenizer that will run basic tokenization (punctuation splitting, lower casing, etc.). + + Args: + do_lower_case (`bool`, *optional*, defaults to `True`): + Whether or not to lowercase the input when tokenizing. + never_split (`Iterable`, *optional*): + Collection of tokens which will never be split during tokenization. Only has an effect when + `do_basic_tokenize=True` + tokenize_chinese_chars (`bool`, *optional*, defaults to `True`): + Whether or not to tokenize Chinese characters. + + This should likely be deactivated for Japanese (see this + [issue](https://github.com/huggingface/transformers/issues/328)). + strip_accents (`bool`, *optional*): + Whether or not to strip all accents. If this option is not specified, then it will be determined by the + value for `lowercase` (as in the original BERT). + do_split_on_punc (`bool`, *optional*, defaults to `True`): + In some instances we want to skip the basic punctuation splitting so that later tokenization can capture + the full context of the words, such as contractions. + """ + + def __init__( + self, + do_lower_case=True, + never_split=None, + tokenize_chinese_chars=True, + strip_accents=None, + do_split_on_punc=True, + ): + if never_split is None: + never_split = [] + self.do_lower_case = do_lower_case + self.never_split = set(never_split) + self.tokenize_chinese_chars = tokenize_chinese_chars + self.strip_accents = strip_accents + self.do_split_on_punc = do_split_on_punc + + def tokenize(self, text, never_split=None): + """ + Basic Tokenization of a piece of text. For sub-word tokenization, see WordPieceTokenizer. + + Args: + never_split (`List[str]`, *optional*) + Kept for backward compatibility purposes. Now implemented directly at the base class level (see + [`PreTrainedTokenizer.tokenize`]) List of token not to split. + """ + # union() returns a new set by concatenating the two sets. + never_split = self.never_split.union(set(never_split)) if never_split else self.never_split + text = self._clean_text(text) + + # This was added on November 1st, 2018 for the multilingual and Chinese + # models. This is also applied to the English models now, but it doesn't + # matter since the English models were not trained on any Chinese data + # and generally don't have any Chinese data in them (there are Chinese + # characters in the vocabulary because Wikipedia does have some Chinese + # words in the English Wikipedia.). + if self.tokenize_chinese_chars: + text = self._tokenize_chinese_chars(text) + # prevents treating the same character with different unicode codepoints as different characters + unicode_normalized_text = unicodedata.normalize("NFC", text) + orig_tokens = whitespace_tokenize(unicode_normalized_text) + split_tokens = [] + for token in orig_tokens: + if token not in never_split: + if self.do_lower_case: + token = token.lower() + if self.strip_accents is not False: + token = self._run_strip_accents(token) + elif self.strip_accents: + token = self._run_strip_accents(token) + split_tokens.extend(self._run_split_on_punc(token, never_split)) + + output_tokens = whitespace_tokenize(" ".join(split_tokens)) + return output_tokens + + def _run_strip_accents(self, text): + """Strips accents from a piece of text.""" + text = unicodedata.normalize("NFD", text) + output = [] + for char in text: + cat = unicodedata.category(char) + if cat == "Mn": + continue + output.append(char) + return "".join(output) + + def _run_split_on_punc(self, text, never_split=None): + """Splits punctuation on a piece of text.""" + if not self.do_split_on_punc or (never_split is not None and text in never_split): + return [text] + chars = list(text) + i = 0 + start_new_word = True + output = [] + while i < len(chars): + char = chars[i] + if _is_punctuation(char): + output.append([char]) + start_new_word = True + else: + if start_new_word: + output.append([]) + start_new_word = False + output[-1].append(char) + i += 1 + + return ["".join(x) for x in output] + + def _tokenize_chinese_chars(self, text): + """Adds whitespace around any CJK character.""" + output = [] + for char in text: + cp = ord(char) + if self._is_chinese_char(cp): + output.append(" ") + output.append(char) + output.append(" ") + else: + output.append(char) + return "".join(output) + + def _is_chinese_char(self, cp): + """Checks whether CP is the codepoint of a CJK character.""" + # This defines a "chinese character" as anything in the CJK Unicode block: + # https://en.wikipedia.org/wiki/CJK_Unified_Ideographs_(Unicode_block) + # + # Note that the CJK Unicode block is NOT all Japanese and Korean characters, + # despite its name. The modern Korean Hangul alphabet is a different block, + # as is Japanese Hiragana and Katakana. Those alphabets are used to write + # space-separated words, so they are not treated specially and handled + # like the all of the other languages. + if ( + (cp >= 0x4E00 and cp <= 0x9FFF) + or (cp >= 0x3400 and cp <= 0x4DBF) + or (cp >= 0x20000 and cp <= 0x2A6DF) + or (cp >= 0x2A700 and cp <= 0x2B73F) + or (cp >= 0x2B740 and cp <= 0x2B81F) + or (cp >= 0x2B820 and cp <= 0x2CEAF) + or (cp >= 0xF900 and cp <= 0xFAFF) + or (cp >= 0x2F800 and cp <= 0x2FA1F) + ): + return True + + return False + + def _clean_text(self, text): + """Performs invalid character removal and whitespace cleanup on text.""" + output = [] + for char in text: + cp = ord(char) + if cp == 0 or cp == 0xFFFD or _is_control(char): + continue + if _is_whitespace(char): + output.append(" ") + else: + output.append(char) + return "".join(output) + + +class WordpieceTokenizer: + """Runs WordPiece tokenization.""" + + def __init__(self, vocab, unk_token, max_input_chars_per_word=100): + self.vocab = vocab + self.unk_token = unk_token + self.max_input_chars_per_word = max_input_chars_per_word + + def tokenize(self, text): + """ + Tokenizes a piece of text into its word pieces. This uses a greedy longest-match-first algorithm to perform + tokenization using the given vocabulary. + + For example, `input = "unaffable"` will return as output `["un", "##aff", "##able"]`. + + Args: + text: A single token or whitespace separated tokens. This should have + already been passed through *BasicTokenizer*. + + Returns: + A list of wordpiece tokens. + """ + + output_tokens = [] + for token in whitespace_tokenize(text): + chars = list(token) + if len(chars) > self.max_input_chars_per_word: + output_tokens.append(self.unk_token) + continue + + is_bad = False + start = 0 + sub_tokens = [] + while start < len(chars): + end = len(chars) + cur_substr = None + while start < end: + substr = "".join(chars[start:end]) + if start > 0: + substr = "##" + substr + if substr in self.vocab: + cur_substr = substr + break + end -= 1 + if cur_substr is None: + is_bad = True + break + sub_tokens.append(cur_substr) + start = end + + if is_bad: + output_tokens.append(self.unk_token) + else: + output_tokens.extend(sub_tokens) + return output_tokens + + +def load_vocab(vocab_file): + """Loads a vocabulary file into a dictionary.""" + vocab = collections.OrderedDict() + with open(vocab_file, "r", encoding="utf-8") as reader: + tokens = reader.readlines() + for index, token in enumerate(tokens): + token = token.rstrip("\n") + vocab[token] = index + return vocab + + +class ProphetNetTokenizer(PreTrainedTokenizer): + r""" + Construct a ProphetNetTokenizer. Based on WordPiece. + + This tokenizer inherits from [`PreTrainedTokenizer`] which contains most of the main methods. Users should refer to + this superclass for more information regarding those methods. + + Args: + vocab_file (`str`): + File containing the vocabulary. + do_lower_case (`bool`, *optional*, defaults to `True`): + Whether or not to lowercase the input when tokenizing. + do_basic_tokenize (`bool`, *optional*, defaults to `True`): + Whether or not to do basic tokenization before WordPiece. + never_split (`Iterable`, *optional*): + Collection of tokens which will never be split during tokenization. Only has an effect when + `do_basic_tokenize=True` + unk_token (`str`, *optional*, defaults to `"[UNK]"`): + The unknown token. A token that is not in the vocabulary cannot be converted to an ID and is set to be this + token instead. + sep_token (`str`, *optional*, defaults to `"[SEP]"`): + The separator token, which is used when building a sequence from multiple sequences, e.g. two sequences for + sequence classification or for a text and a question for question answering. It is also used as the last + token of a sequence built with special tokens. + x_sep_token (`str`, *optional*, defaults to `"[X_SEP]"`): + Special second separator token, which can be generated by [`ProphetNetForConditionalGeneration`]. It is + used to separate bullet-point like sentences in summarization, *e.g.*. + pad_token (`str`, *optional*, defaults to `"[PAD]"`): + The token used for padding, for example when batching sequences of different lengths. + mask_token (`str`, *optional*, defaults to `"[MASK]"`): + The token used for masking values. This is the token used when training this model with masked language + modeling. This is the token which the model will try to predict. + tokenize_chinese_chars (`bool`, *optional*, defaults to `True`): + Whether or not to tokenize Chinese characters. + + This should likely be deactivated for Japanese (see this + [issue](https://github.com/huggingface/transformers/issues/328)). + strip_accents (`bool`, *optional*): + Whether or not to strip all accents. If this option is not specified, then it will be determined by the + value for `lowercase` (as in the original BERT). + clean_up_tokenization_spaces (`bool`, *optional*, defaults to `True`): + Whether or not to cleanup spaces after decoding, cleanup consists in removing potential artifacts like + extra spaces. + """ + + vocab_files_names = VOCAB_FILES_NAMES + + # first name has to correspond to main model input name + # to make sure `tokenizer.pad(...)` works correctly + # `ProphetNet` doesn't have `token_type_ids` as argument. + model_input_names: list[str] = ["input_ids", "attention_mask"] + + def __init__( + self, + vocab_file: str, + do_lower_case: bool | None = True, + do_basic_tokenize: bool | None = True, + never_split: Iterable | None = None, + unk_token: str | None = "[UNK]", + sep_token: str | None = "[SEP]", + x_sep_token: str | None = "[X_SEP]", + pad_token: str | None = "[PAD]", + mask_token: str | None = "[MASK]", + tokenize_chinese_chars: bool | None = True, + strip_accents: bool | None = None, + clean_up_tokenization_spaces: bool = True, + **kwargs, + ): + if not os.path.isfile(vocab_file): + raise ValueError( + f"Can't find a vocabulary file at path '{vocab_file}'. To load the vocabulary from a Google pretrained" + " model use `tokenizer = AutoTokenizer.from_pretrained(PRETRAINED_MODEL_NAME)`" + ) + self.vocab = load_vocab(vocab_file) + self.ids_to_tokens = collections.OrderedDict([(ids, tok) for tok, ids in self.vocab.items()]) + self.do_basic_tokenize = do_basic_tokenize + if do_basic_tokenize: + self.basic_tokenizer = BasicTokenizer( + do_lower_case=do_lower_case, + never_split=never_split, + tokenize_chinese_chars=tokenize_chinese_chars, + strip_accents=strip_accents, + ) + self.wordpiece_tokenizer = WordpieceTokenizer(vocab=self.vocab, unk_token=str(unk_token)) + + super().__init__( + do_lower_case=do_lower_case, + do_basic_tokenize=do_basic_tokenize, + never_split=never_split, + unk_token=unk_token, + sep_token=sep_token, + x_sep_token=x_sep_token, + pad_token=pad_token, + mask_token=mask_token, + tokenize_chinese_chars=tokenize_chinese_chars, + strip_accents=strip_accents, + clean_up_tokenization_spaces=clean_up_tokenization_spaces, + **kwargs, + ) + + @property + def vocab_size(self): + return len(self.vocab) + + def get_vocab(self): + return dict(self.vocab, **self.added_tokens_encoder) + + def _tokenize(self, text): + split_tokens = [] + if self.do_basic_tokenize: + for token in self.basic_tokenizer.tokenize(text, never_split=self.all_special_tokens): + # If the token is part of the never_split set + if token in self.basic_tokenizer.never_split: + split_tokens.append(token) + else: + split_tokens += self.wordpiece_tokenizer.tokenize(token) + else: + split_tokens = self.wordpiece_tokenizer.tokenize(text) + return split_tokens + + def _convert_token_to_id(self, token: str): + """Converts a token (str) in an id using the vocab.""" + return self.vocab.get(token, self.vocab.get(self.unk_token)) + + def _convert_id_to_token(self, index: int): + """Converts an index (integer) in a token (str) using the vocab.""" + return self.ids_to_tokens.get(index, self.unk_token) + + def convert_tokens_to_string(self, tokens: str): + """Converts a sequence of tokens (string) in a single string.""" + out_string = " ".join(tokens).replace(" ##", "").strip() + return out_string + + def get_special_tokens_mask( + self, + token_ids_0: list[int], + token_ids_1: list[int] | None = None, + already_has_special_tokens: bool | None = False, + ) -> list[int]: + """ + Retrieve sequence ids from a token list that has no special tokens added. This method is called when adding + special tokens using the tokenizer `prepare_for_model` method. + + Args: + token_ids_0 (`List[int]`): + List of IDs. + token_ids_1 (`List[int]`, *optional*): + Optional second list of IDs for sequence pairs. + already_has_special_tokens (`bool`, *optional*, defaults to `False`): + Whether or not the token list is already formatted with special tokens for the model. + + Returns: + `List[int]`: A list of integers in the range [0, 1]: 1 for a special token, 0 for a sequence token. + """ + if already_has_special_tokens: + return super().get_special_tokens_mask( + token_ids_0=token_ids_0, token_ids_1=token_ids_1, already_has_special_tokens=True + ) + + if token_ids_1 is None: + return ([0] * len(token_ids_0)) + [1] + return ([0] * len(token_ids_0)) + [1] + ([0] * len(token_ids_1)) + [1] + + def save_vocabulary(self, save_directory: str, filename_prefix: str | None = None) -> tuple[str]: + index = 0 + if os.path.isdir(save_directory): + vocab_file = os.path.join( + save_directory, (filename_prefix + "-" if filename_prefix else "") + VOCAB_FILES_NAMES["vocab_file"] + ) + else: + vocab_file = (filename_prefix + "-" if filename_prefix else "") + save_directory + with open(vocab_file, "w", encoding="utf-8") as writer: + for token, token_index in sorted(self.vocab.items(), key=lambda kv: kv[1]): + if index != token_index: + logger.warning( + f"Saving vocabulary to {vocab_file}: vocabulary indices are not consecutive." + " Please check that the vocabulary is not corrupted!" + ) + index = token_index + writer.write(token + "\n") + index += 1 + return (vocab_file,) + + def build_inputs_with_special_tokens( + self, token_ids_0: list[int], token_ids_1: list[int] | None = None + ) -> list[int]: + """ + Build model inputs from a sequence or a pair of sequence for sequence classification tasks by concatenating and + adding special tokens. A BERT sequence has the following format: + + - single sequence: `[CLS] X [SEP]` + - pair of sequences: `[CLS] A [SEP] B [SEP]` + + Args: + token_ids_0 (`List[int]`): + List of IDs to which the special tokens will be added. + token_ids_1 (`List[int]`, *optional*): + Optional second list of IDs for sequence pairs. + + Returns: + `List[int]`: List of [input IDs](../glossary#input-ids) with the appropriate special tokens. + """ + if token_ids_1 is None: + return token_ids_0 + [self.sep_token_id] + sep = [self.sep_token_id] + return token_ids_0 + sep + token_ids_1 + sep + + +__all__ = ["ProphetNetTokenizer"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pvt/__init__.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pvt/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..371478776da01819236b470d7a96717003a26d74 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pvt/__init__.py @@ -0,0 +1,29 @@ +# Copyright 2024 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from typing import TYPE_CHECKING + +from ...utils import _LazyModule +from ...utils.import_utils import define_import_structure + + +if TYPE_CHECKING: + from .configuration_pvt import * + from .image_processing_pvt import * + from .image_processing_pvt_fast import * + from .modeling_pvt import * +else: + import sys + + _file = globals()["__file__"] + sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__) diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pvt/configuration_pvt.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pvt/configuration_pvt.py new file mode 100644 index 0000000000000000000000000000000000000000..08446452fe2bf5a3ed6dd464a65bbc30aba205b0 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pvt/configuration_pvt.py @@ -0,0 +1,137 @@ +# Copyright 2023 Authors: Wenhai Wang, Enze Xie, Xiang Li, Deng-Ping Fan, +# Kaitao Song, Ding Liang, Tong Lu, Ping Luo, Ling Shao and The HuggingFace Inc. team. +# All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""Pvt model configuration""" + +from collections.abc import Callable, Mapping + +from ...configuration_utils import PreTrainedConfig +from ...utils import logging + + +logger = logging.get_logger(__name__) + + +class PvtConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`PvtModel`]. It is used to instantiate an Pvt + model according to the specified arguments, defining the model architecture. Instantiating a configuration with the + defaults will yield a similar configuration to that of the Pvt + [Xrenya/pvt-tiny-224](https://huggingface.co/Xrenya/pvt-tiny-224) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + image_size (`int`, *optional*, defaults to 224): + The input image size + num_channels (`int`, *optional*, defaults to 3): + The number of input channels. + num_encoder_blocks (`int`, *optional*, defaults to 4): + The number of encoder blocks (i.e. stages in the Mix Transformer encoder). + depths (`list[int]`, *optional*, defaults to `[2, 2, 2, 2]`): + The number of layers in each encoder block. + sequence_reduction_ratios (`list[int]`, *optional*, defaults to `[8, 4, 2, 1]`): + Sequence reduction ratios in each encoder block. + hidden_sizes (`list[int]`, *optional*, defaults to `[64, 128, 320, 512]`): + Dimension of each of the encoder blocks. + patch_sizes (`list[int]`, *optional*, defaults to `[4, 2, 2, 2]`): + Patch size before each encoder block. + strides (`list[int]`, *optional*, defaults to `[4, 2, 2, 2]`): + Stride before each encoder block. + num_attention_heads (`list[int]`, *optional*, defaults to `[1, 2, 5, 8]`): + Number of attention heads for each attention layer in each block of the Transformer encoder. + mlp_ratios (`list[int]`, *optional*, defaults to `[8, 8, 4, 4]`): + Ratio of the size of the hidden layer compared to the size of the input layer of the Mix FFNs in the + encoder blocks. + hidden_act (`str` or `function`, *optional*, defaults to `"gelu"`): + The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`, + `"relu"`, `"selu"` and `"gelu_new"` are supported. + hidden_dropout_prob (`float`, *optional*, defaults to 0.0): + The dropout probability for all fully connected layers in the embeddings, encoder, and pooler. + attention_probs_dropout_prob (`float`, *optional*, defaults to 0.0): + The dropout ratio for the attention probabilities. + initializer_range (`float`, *optional*, defaults to 0.02): + The standard deviation of the truncated_normal_initializer for initializing all weight matrices. + drop_path_rate (`float`, *optional*, defaults to 0.0): + The dropout probability for stochastic depth, used in the blocks of the Transformer encoder. + layer_norm_eps (`float`, *optional*, defaults to 1e-06): + The epsilon used by the layer normalization layers. + qkv_bias (`bool`, *optional*, defaults to `True`): + Whether or not a learnable bias should be added to the queries, keys and values. + num_labels ('int', *optional*, defaults to 1000): + The number of classes. + Example: + + ```python + >>> from transformers import PvtModel, PvtConfig + + >>> # Initializing a PVT Xrenya/pvt-tiny-224 style configuration + >>> configuration = PvtConfig() + + >>> # Initializing a model from the Xrenya/pvt-tiny-224 style configuration + >>> model = PvtModel(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "pvt" + + def __init__( + self, + image_size: int = 224, + num_channels: int = 3, + num_encoder_blocks: int = 4, + depths: list[int] = [2, 2, 2, 2], + sequence_reduction_ratios: list[int] = [8, 4, 2, 1], + hidden_sizes: list[int] = [64, 128, 320, 512], + patch_sizes: list[int] = [4, 2, 2, 2], + strides: list[int] = [4, 2, 2, 2], + num_attention_heads: list[int] = [1, 2, 5, 8], + mlp_ratios: list[int] = [8, 8, 4, 4], + hidden_act: Mapping[str, Callable] = "gelu", + hidden_dropout_prob: float = 0.0, + attention_probs_dropout_prob: float = 0.0, + initializer_range: float = 0.02, + drop_path_rate: float = 0.0, + layer_norm_eps: float = 1e-6, + qkv_bias: bool = True, + num_labels: int = 1000, + **kwargs, + ): + super().__init__(**kwargs) + + self.image_size = image_size + self.num_channels = num_channels + self.num_encoder_blocks = num_encoder_blocks + self.depths = depths + self.sequence_reduction_ratios = sequence_reduction_ratios + self.hidden_sizes = hidden_sizes + self.patch_sizes = patch_sizes + self.strides = strides + self.mlp_ratios = mlp_ratios + self.num_attention_heads = num_attention_heads + self.hidden_act = hidden_act + self.hidden_dropout_prob = hidden_dropout_prob + self.attention_probs_dropout_prob = attention_probs_dropout_prob + self.initializer_range = initializer_range + self.drop_path_rate = drop_path_rate + self.layer_norm_eps = layer_norm_eps + self.num_labels = num_labels + self.qkv_bias = qkv_bias + + +__all__ = ["PvtConfig"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pvt/image_processing_pvt.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pvt/image_processing_pvt.py new file mode 100644 index 0000000000000000000000000000000000000000..1364e480a92a0dbc48a72723924dce9479d18280 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pvt/image_processing_pvt.py @@ -0,0 +1,268 @@ +# Copyright 2023 The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""Image processor class for Pvt.""" + +import numpy as np + +from ...image_processing_utils import BaseImageProcessor, BatchFeature, get_size_dict +from ...image_transforms import resize, to_channel_dimension_format +from ...image_utils import ( + IMAGENET_DEFAULT_MEAN, + IMAGENET_DEFAULT_STD, + ChannelDimension, + ImageInput, + PILImageResampling, + infer_channel_dimension_format, + is_scaled_image, + make_flat_list_of_images, + to_numpy_array, + valid_images, + validate_preprocess_arguments, +) +from ...utils import TensorType, filter_out_non_signature_kwargs, logging + + +logger = logging.get_logger(__name__) + + +class PvtImageProcessor(BaseImageProcessor): + r""" + Constructs a PVT image processor. + + Args: + do_resize (`bool`, *optional*, defaults to `True`): + Whether to resize the image's (height, width) dimensions to the specified `(size["height"], + size["width"])`. Can be overridden by the `do_resize` parameter in the `preprocess` method. + size (`dict`, *optional*, defaults to `{"height": 224, "width": 224}`): + Size of the output image after resizing. Can be overridden by the `size` parameter in the `preprocess` + method. + resample (`PILImageResampling`, *optional*, defaults to `PILImageResampling.BICUBIC`): + Resampling filter to use if resizing the image. Can be overridden by the `resample` parameter in the + `preprocess` method. + do_rescale (`bool`, *optional*, defaults to `True`): + Whether to rescale the image by the specified scale `rescale_factor`. Can be overridden by the `do_rescale` + parameter in the `preprocess` method. + rescale_factor (`int` or `float`, *optional*, defaults to `1/255`): + Scale factor to use if rescaling the image. Can be overridden by the `rescale_factor` parameter in the + `preprocess` method. + do_normalize (`bool`, *optional*, defaults to `True`): + Whether to normalize the image. Can be overridden by the `do_normalize` parameter in the `preprocess` + method. + image_mean (`float` or `list[float]`, *optional*, defaults to `IMAGENET_DEFAULT_MEAN`): + Mean to use if normalizing the image. This is a float or list of floats the length of the number of + channels in the image. Can be overridden by the `image_mean` parameter in the `preprocess` method. + image_std (`float` or `list[float]`, *optional*, defaults to `IMAGENET_DEFAULT_STD`): + Standard deviation to use if normalizing the image. This is a float or list of floats the length of the + number of channels in the image. Can be overridden by the `image_std` parameter in the `preprocess` method. + """ + + model_input_names = ["pixel_values"] + + def __init__( + self, + do_resize: bool = True, + size: dict[str, int] | None = None, + resample: PILImageResampling = PILImageResampling.BICUBIC, + do_rescale: bool = True, + rescale_factor: int | float = 1 / 255, + do_normalize: bool = True, + image_mean: float | list[float] | None = None, + image_std: float | list[float] | None = None, + **kwargs, + ) -> None: + super().__init__(**kwargs) + size = size if size is not None else {"height": 224, "width": 224} + size = get_size_dict(size) + self.do_resize = do_resize + self.do_rescale = do_rescale + self.do_normalize = do_normalize + self.size = size + self.resample = resample + self.rescale_factor = rescale_factor + self.image_mean = image_mean if image_mean is not None else IMAGENET_DEFAULT_MEAN + self.image_std = image_std if image_std is not None else IMAGENET_DEFAULT_STD + + def resize( + self, + image: np.ndarray, + size: dict[str, int], + resample: PILImageResampling = PILImageResampling.BICUBIC, + data_format: str | ChannelDimension | None = None, + input_data_format: str | ChannelDimension | None = None, + **kwargs, + ) -> np.ndarray: + """ + Resize an image to `(size["height"], size["width"])`. + + Args: + image (`np.ndarray`): + Image to resize. + size (`dict[str, int]`): + Dictionary in the format `{"height": int, "width": int}` specifying the size of the output image. + resample (`PILImageResampling`, *optional*, defaults to `PILImageResampling.BICUBIC`): + `PILImageResampling` filter to use when resizing the image e.g. `PILImageResampling.BICUBIC`. + data_format (`ChannelDimension` or `str`, *optional*): + The channel dimension format for the output image. If unset, the channel dimension format of the input + image is used. Can be one of: + - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format. + - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format. + - `"none"` or `ChannelDimension.NONE`: image in (height, width) format. + input_data_format (`ChannelDimension` or `str`, *optional*): + The channel dimension format for the input image. If unset, the channel dimension format is inferred + from the input image. Can be one of: + - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format. + - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format. + - `"none"` or `ChannelDimension.NONE`: image in (height, width) format. + + Returns: + `np.ndarray`: The resized image. + """ + + size = get_size_dict(size) + if "height" not in size or "width" not in size: + raise ValueError(f"The `size` dictionary must contain the keys `height` and `width`. Got {size.keys()}") + output_size = (size["height"], size["width"]) + return resize( + image, + size=output_size, + resample=resample, + data_format=data_format, + input_data_format=input_data_format, + **kwargs, + ) + + @filter_out_non_signature_kwargs() + def preprocess( + self, + images: ImageInput, + do_resize: bool | None = None, + size: dict[str, int] | None = None, + resample: PILImageResampling | None = None, + do_rescale: bool | None = None, + rescale_factor: float | None = None, + do_normalize: bool | None = None, + image_mean: float | list[float] | None = None, + image_std: float | list[float] | None = None, + return_tensors: str | TensorType | None = None, + data_format: str | ChannelDimension = ChannelDimension.FIRST, + input_data_format: str | ChannelDimension | None = None, + ): + """ + Preprocess an image or batch of images. + + Args: + images (`ImageInput`): + Image to preprocess. Expects a single or batch of images with pixel values ranging from 0 to 255. If + passing in images with pixel values between 0 and 1, set `do_rescale=False`. + do_resize (`bool`, *optional*, defaults to `self.do_resize`): + Whether to resize the image. + size (`dict[str, int]`, *optional*, defaults to `self.size`): + Dictionary in the format `{"height": h, "width": w}` specifying the size of the output image after + resizing. + resample (`PILImageResampling` filter, *optional*, defaults to `self.resample`): + `PILImageResampling` filter to use if resizing the image e.g. `PILImageResampling.BICUBIC`. Only has + an effect if `do_resize` is set to `True`. + do_rescale (`bool`, *optional*, defaults to `self.do_rescale`): + Whether to rescale the image values between [0 - 1]. + rescale_factor (`float`, *optional*, defaults to `self.rescale_factor`): + Rescale factor to rescale the image by if `do_rescale` is set to `True`. + do_normalize (`bool`, *optional*, defaults to `self.do_normalize`): + Whether to normalize the image. + image_mean (`float` or `list[float]`, *optional*, defaults to `self.image_mean`): + Image mean to use if `do_normalize` is set to `True`. + image_std (`float` or `list[float]`, *optional*, defaults to `self.image_std`): + Image standard deviation to use if `do_normalize` is set to `True`. + return_tensors (`str` or `TensorType`, *optional*): + The type of tensors to return. Can be one of: + - Unset: Return a list of `np.ndarray`. + - `TensorType.PYTORCH` or `'pt'`: Return a batch of type `torch.Tensor`. + - `TensorType.NUMPY` or `'np'`: Return a batch of type `np.ndarray`. + data_format (`ChannelDimension` or `str`, *optional*, defaults to `ChannelDimension.FIRST`): + The channel dimension format for the output image. Can be one of: + - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format. + - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format. + - Unset: Use the channel dimension format of the input image. + input_data_format (`ChannelDimension` or `str`, *optional*): + The channel dimension format for the input image. If unset, the channel dimension format is inferred + from the input image. Can be one of: + - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format. + - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format. + - `"none"` or `ChannelDimension.NONE`: image in (height, width) format. + """ + do_resize = do_resize if do_resize is not None else self.do_resize + do_rescale = do_rescale if do_rescale is not None else self.do_rescale + do_normalize = do_normalize if do_normalize is not None else self.do_normalize + resample = resample if resample is not None else self.resample + rescale_factor = rescale_factor if rescale_factor is not None else self.rescale_factor + image_mean = image_mean if image_mean is not None else self.image_mean + image_std = image_std if image_std is not None else self.image_std + + size = size if size is not None else self.size + size_dict = get_size_dict(size) + + images = make_flat_list_of_images(images) + + if not valid_images(images): + raise ValueError("Invalid image type. Must be of type PIL.Image.Image, numpy.ndarray, or torch.Tensor") + validate_preprocess_arguments( + do_rescale=do_rescale, + rescale_factor=rescale_factor, + do_normalize=do_normalize, + image_mean=image_mean, + image_std=image_std, + do_resize=do_resize, + size=size, + resample=resample, + ) + + # All transformations expect numpy arrays. + images = [to_numpy_array(image) for image in images] + + if do_rescale and is_scaled_image(images[0]): + logger.warning_once( + "It looks like you are trying to rescale already rescaled images. If the input" + " images have pixel values between 0 and 1, set `do_rescale=False` to avoid rescaling them again." + ) + + if input_data_format is None: + # We assume that all images have the same channel dimension format. + input_data_format = infer_channel_dimension_format(images[0]) + + if do_resize: + images = [ + self.resize(image=image, size=size_dict, resample=resample, input_data_format=input_data_format) + for image in images + ] + + if do_rescale: + images = [ + self.rescale(image=image, scale=rescale_factor, input_data_format=input_data_format) + for image in images + ] + + if do_normalize: + images = [ + self.normalize(image=image, mean=image_mean, std=image_std, input_data_format=input_data_format) + for image in images + ] + + images = [ + to_channel_dimension_format(image, data_format, input_channel_dim=input_data_format) for image in images + ] + + data = {"pixel_values": images} + return BatchFeature(data=data, tensor_type=return_tensors) + + +__all__ = ["PvtImageProcessor"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pvt/image_processing_pvt_fast.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pvt/image_processing_pvt_fast.py new file mode 100644 index 0000000000000000000000000000000000000000..d2ade912a1675a648082487b16137386a9aac526 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pvt/image_processing_pvt_fast.py @@ -0,0 +1,37 @@ +# Copyright 2025 The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""Fast Image processor class for Pvt.""" + +from ...image_processing_utils_fast import BaseImageProcessorFast +from ...image_utils import IMAGENET_DEFAULT_MEAN, IMAGENET_DEFAULT_STD, PILImageResampling +from ...utils import auto_docstring + + +@auto_docstring +class PvtImageProcessorFast(BaseImageProcessorFast): + resample = PILImageResampling.BICUBIC + image_mean = IMAGENET_DEFAULT_MEAN + image_std = IMAGENET_DEFAULT_STD + size = {"height": 224, "width": 224} + default_to_square = True + crop_size = None + do_resize = True + do_center_crop = None + do_rescale = True + do_normalize = True + do_convert_rgb = None + model_input_names = ["pixel_values"] + + +__all__ = ["PvtImageProcessorFast"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pvt/modeling_pvt.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pvt/modeling_pvt.py new file mode 100644 index 0000000000000000000000000000000000000000..dd22b7a1c5d7ba9410d014b2f6ba859ca63e63aa --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pvt/modeling_pvt.py @@ -0,0 +1,551 @@ +# Copyright 2023 Authors: Wenhai Wang, Enze Xie, Xiang Li, Deng-Ping Fan, +# Kaitao Song, Ding Liang, Tong Lu, Ping Luo, Ling Shao and The HuggingFace Inc. team. +# All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""PyTorch PVT model.""" + +import collections +import math +from collections.abc import Iterable + +import torch +import torch.nn.functional as F +from torch import nn + +from ... import initialization as init +from ...activations import ACT2FN +from ...modeling_outputs import BaseModelOutput, ImageClassifierOutput +from ...modeling_utils import PreTrainedModel +from ...utils import auto_docstring, logging +from .configuration_pvt import PvtConfig + + +logger = logging.get_logger(__name__) + + +# Copied from transformers.models.beit.modeling_beit.drop_path +def drop_path(input: torch.Tensor, drop_prob: float = 0.0, training: bool = False) -> torch.Tensor: + """ + Drop paths (Stochastic Depth) per sample (when applied in main path of residual blocks). + + """ + if drop_prob == 0.0 or not training: + return input + keep_prob = 1 - drop_prob + shape = (input.shape[0],) + (1,) * (input.ndim - 1) # work with diff dim tensors, not just 2D ConvNets + random_tensor = keep_prob + torch.rand(shape, dtype=input.dtype, device=input.device) + random_tensor.floor_() # binarize + output = input.div(keep_prob) * random_tensor + return output + + +# Copied from transformers.models.convnext.modeling_convnext.ConvNextDropPath with ConvNext->Pvt +class PvtDropPath(nn.Module): + """Drop paths (Stochastic Depth) per sample (when applied in main path of residual blocks).""" + + def __init__(self, drop_prob: float | None = None) -> None: + super().__init__() + self.drop_prob = drop_prob + + def forward(self, hidden_states: torch.Tensor) -> torch.Tensor: + return drop_path(hidden_states, self.drop_prob, self.training) + + def extra_repr(self) -> str: + return f"p={self.drop_prob}" + + +class PvtPatchEmbeddings(nn.Module): + """ + This class turns `pixel_values` of shape `(batch_size, num_channels, height, width)` into the initial + `hidden_states` (patch embeddings) of shape `(batch_size, seq_length, hidden_size)` to be consumed by a + Transformer. + """ + + def __init__( + self, + config: PvtConfig, + image_size: int | Iterable[int], + patch_size: int | Iterable[int], + stride: int, + num_channels: int, + hidden_size: int, + cls_token: bool = False, + ): + super().__init__() + self.config = config + image_size = image_size if isinstance(image_size, collections.abc.Iterable) else (image_size, image_size) + patch_size = patch_size if isinstance(patch_size, collections.abc.Iterable) else (patch_size, patch_size) + num_patches = (image_size[1] // patch_size[1]) * (image_size[0] // patch_size[0]) + self.image_size = image_size + self.patch_size = patch_size + self.num_channels = num_channels + self.num_patches = num_patches + + self.position_embeddings = nn.Parameter( + torch.randn(1, num_patches + 1 if cls_token else num_patches, hidden_size) + ) + self.cls_token = nn.Parameter(torch.zeros(1, 1, hidden_size)) if cls_token else None + self.projection = nn.Conv2d(num_channels, hidden_size, kernel_size=stride, stride=patch_size) + self.layer_norm = nn.LayerNorm(hidden_size, eps=config.layer_norm_eps) + self.dropout = nn.Dropout(p=config.hidden_dropout_prob) + + def interpolate_pos_encoding(self, embeddings: torch.Tensor, height: int, width: int) -> torch.Tensor: + num_patches = height * width + + # always interpolate when tracing to ensure the exported model works for dynamic input shapes + if not torch.jit.is_tracing() and num_patches == self.config.image_size * self.config.image_size: + return self.position_embeddings + embeddings = embeddings.reshape(1, height, width, -1).permute(0, 3, 1, 2) + interpolated_embeddings = F.interpolate(embeddings, size=(height, width), mode="bilinear") + interpolated_embeddings = interpolated_embeddings.reshape(1, -1, height * width).permute(0, 2, 1) + return interpolated_embeddings + + def forward(self, pixel_values: torch.Tensor) -> tuple[torch.Tensor, int, int]: + batch_size, num_channels, height, width = pixel_values.shape + if num_channels != self.num_channels: + raise ValueError( + "Make sure that the channel dimension of the pixel values match with the one set in the configuration." + ) + patch_embed = self.projection(pixel_values) + *_, height, width = patch_embed.shape + patch_embed = patch_embed.flatten(2).transpose(1, 2) + embeddings = self.layer_norm(patch_embed) + if self.cls_token is not None: + cls_token = self.cls_token.expand(batch_size, -1, -1) + embeddings = torch.cat((cls_token, embeddings), dim=1) + position_embeddings = self.interpolate_pos_encoding(self.position_embeddings[:, 1:], height, width) + position_embeddings = torch.cat((self.position_embeddings[:, :1], position_embeddings), dim=1) + else: + position_embeddings = self.interpolate_pos_encoding(self.position_embeddings, height, width) + embeddings = self.dropout(embeddings + position_embeddings) + + return embeddings, height, width + + +class PvtSelfOutput(nn.Module): + def __init__(self, config: PvtConfig, hidden_size: int): + super().__init__() + self.dense = nn.Linear(hidden_size, hidden_size) + self.dropout = nn.Dropout(config.hidden_dropout_prob) + + def forward(self, hidden_states: torch.Tensor) -> torch.Tensor: + hidden_states = self.dense(hidden_states) + hidden_states = self.dropout(hidden_states) + return hidden_states + + +class PvtEfficientSelfAttention(nn.Module): + """Efficient self-attention mechanism with reduction of the sequence [PvT paper](https://huggingface.co/papers/2102.12122).""" + + def __init__( + self, config: PvtConfig, hidden_size: int, num_attention_heads: int, sequences_reduction_ratio: float + ): + super().__init__() + self.hidden_size = hidden_size + self.num_attention_heads = num_attention_heads + + if self.hidden_size % self.num_attention_heads != 0: + raise ValueError( + f"The hidden size ({self.hidden_size}) is not a multiple of the number of attention " + f"heads ({self.num_attention_heads})" + ) + + self.attention_head_size = int(self.hidden_size / self.num_attention_heads) + self.all_head_size = self.num_attention_heads * self.attention_head_size + + self.query = nn.Linear(self.hidden_size, self.all_head_size, bias=config.qkv_bias) + self.key = nn.Linear(self.hidden_size, self.all_head_size, bias=config.qkv_bias) + self.value = nn.Linear(self.hidden_size, self.all_head_size, bias=config.qkv_bias) + + self.dropout = nn.Dropout(config.attention_probs_dropout_prob) + + self.sequences_reduction_ratio = sequences_reduction_ratio + if sequences_reduction_ratio > 1: + self.sequence_reduction = nn.Conv2d( + hidden_size, hidden_size, kernel_size=sequences_reduction_ratio, stride=sequences_reduction_ratio + ) + self.layer_norm = nn.LayerNorm(hidden_size, eps=config.layer_norm_eps) + + def transpose_for_scores(self, hidden_states: int) -> torch.Tensor: + new_shape = hidden_states.size()[:-1] + (self.num_attention_heads, self.attention_head_size) + hidden_states = hidden_states.view(new_shape) + return hidden_states.permute(0, 2, 1, 3) + + def forward( + self, + hidden_states: torch.Tensor, + height: int, + width: int, + output_attentions: bool = False, + ) -> tuple[torch.Tensor]: + query_layer = self.transpose_for_scores(self.query(hidden_states)) + + if self.sequences_reduction_ratio > 1: + batch_size, seq_len, num_channels = hidden_states.shape + # Reshape to (batch_size, num_channels, height, width) + hidden_states = hidden_states.permute(0, 2, 1).reshape(batch_size, num_channels, height, width) + # Apply sequence reduction + hidden_states = self.sequence_reduction(hidden_states) + # Reshape back to (batch_size, seq_len, num_channels) + hidden_states = hidden_states.reshape(batch_size, num_channels, -1).permute(0, 2, 1) + hidden_states = self.layer_norm(hidden_states) + + key_layer = self.transpose_for_scores(self.key(hidden_states)) + value_layer = self.transpose_for_scores(self.value(hidden_states)) + + # Take the dot product between "query" and "key" to get the raw attention scores. + attention_scores = torch.matmul(query_layer, key_layer.transpose(-1, -2)) + + attention_scores = attention_scores / math.sqrt(self.attention_head_size) + + # Normalize the attention scores to probabilities. + attention_probs = nn.functional.softmax(attention_scores, dim=-1) + + # This is actually dropping out entire tokens to attend to, which might + # seem a bit unusual, but is taken from the original Transformer paper. + attention_probs = self.dropout(attention_probs) + + context_layer = torch.matmul(attention_probs, value_layer) + + context_layer = context_layer.permute(0, 2, 1, 3).contiguous() + new_context_layer_shape = context_layer.size()[:-2] + (self.all_head_size,) + context_layer = context_layer.view(new_context_layer_shape) + + outputs = (context_layer, attention_probs) if output_attentions else (context_layer,) + + return outputs + + +class PvtAttention(nn.Module): + def __init__( + self, config: PvtConfig, hidden_size: int, num_attention_heads: int, sequences_reduction_ratio: float + ): + super().__init__() + self.self = PvtEfficientSelfAttention( + config, + hidden_size=hidden_size, + num_attention_heads=num_attention_heads, + sequences_reduction_ratio=sequences_reduction_ratio, + ) + self.output = PvtSelfOutput(config, hidden_size=hidden_size) + + def forward( + self, hidden_states: torch.Tensor, height: int, width: int, output_attentions: bool = False + ) -> tuple[torch.Tensor]: + self_outputs = self.self(hidden_states, height, width, output_attentions) + + attention_output = self.output(self_outputs[0]) + outputs = (attention_output,) + self_outputs[1:] # add attentions if we output them + return outputs + + +class PvtFFN(nn.Module): + def __init__( + self, + config: PvtConfig, + in_features: int, + hidden_features: int | None = None, + out_features: int | None = None, + ): + super().__init__() + out_features = out_features if out_features is not None else in_features + self.dense1 = nn.Linear(in_features, hidden_features) + if isinstance(config.hidden_act, str): + self.intermediate_act_fn = ACT2FN[config.hidden_act] + else: + self.intermediate_act_fn = config.hidden_act + self.dense2 = nn.Linear(hidden_features, out_features) + self.dropout = nn.Dropout(config.hidden_dropout_prob) + + def forward(self, hidden_states: torch.Tensor) -> torch.Tensor: + hidden_states = self.dense1(hidden_states) + hidden_states = self.intermediate_act_fn(hidden_states) + hidden_states = self.dropout(hidden_states) + hidden_states = self.dense2(hidden_states) + hidden_states = self.dropout(hidden_states) + return hidden_states + + +class PvtLayer(nn.Module): + def __init__( + self, + config: PvtConfig, + hidden_size: int, + num_attention_heads: int, + drop_path: float, + sequences_reduction_ratio: float, + mlp_ratio: float, + ): + super().__init__() + self.layer_norm_1 = nn.LayerNorm(hidden_size, eps=config.layer_norm_eps) + self.attention = PvtAttention( + config=config, + hidden_size=hidden_size, + num_attention_heads=num_attention_heads, + sequences_reduction_ratio=sequences_reduction_ratio, + ) + self.drop_path = PvtDropPath(drop_path) if drop_path > 0.0 else nn.Identity() + self.layer_norm_2 = nn.LayerNorm(hidden_size, eps=config.layer_norm_eps) + mlp_hidden_size = int(hidden_size * mlp_ratio) + self.mlp = PvtFFN(config=config, in_features=hidden_size, hidden_features=mlp_hidden_size) + + def forward(self, hidden_states: torch.Tensor, height: int, width: int, output_attentions: bool = False): + self_attention_outputs = self.attention( + hidden_states=self.layer_norm_1(hidden_states), + height=height, + width=width, + output_attentions=output_attentions, + ) + attention_output = self_attention_outputs[0] + outputs = self_attention_outputs[1:] + + attention_output = self.drop_path(attention_output) + hidden_states = attention_output + hidden_states + + mlp_output = self.mlp(self.layer_norm_2(hidden_states)) + + mlp_output = self.drop_path(mlp_output) + layer_output = hidden_states + mlp_output + + outputs = (layer_output,) + outputs + + return outputs + + +class PvtEncoder(nn.Module): + def __init__(self, config: PvtConfig): + super().__init__() + self.config = config + + # stochastic depth decay rule + drop_path_decays = torch.linspace(0, config.drop_path_rate, sum(config.depths), device="cpu").tolist() + + # patch embeddings + embeddings = [] + + for i in range(config.num_encoder_blocks): + embeddings.append( + PvtPatchEmbeddings( + config=config, + image_size=config.image_size if i == 0 else self.config.image_size // (2 ** (i + 1)), + patch_size=config.patch_sizes[i], + stride=config.strides[i], + num_channels=config.num_channels if i == 0 else config.hidden_sizes[i - 1], + hidden_size=config.hidden_sizes[i], + cls_token=i == config.num_encoder_blocks - 1, + ) + ) + self.patch_embeddings = nn.ModuleList(embeddings) + + # Transformer blocks + blocks = [] + cur = 0 + for i in range(config.num_encoder_blocks): + # each block consists of layers + layers = [] + if i != 0: + cur += config.depths[i - 1] + for j in range(config.depths[i]): + layers.append( + PvtLayer( + config=config, + hidden_size=config.hidden_sizes[i], + num_attention_heads=config.num_attention_heads[i], + drop_path=drop_path_decays[cur + j], + sequences_reduction_ratio=config.sequence_reduction_ratios[i], + mlp_ratio=config.mlp_ratios[i], + ) + ) + blocks.append(nn.ModuleList(layers)) + + self.block = nn.ModuleList(blocks) + + # Layer norms + self.layer_norm = nn.LayerNorm(config.hidden_sizes[-1], eps=config.layer_norm_eps) + + def forward( + self, + pixel_values: torch.FloatTensor, + output_attentions: bool | None = False, + output_hidden_states: bool | None = False, + return_dict: bool | None = True, + ) -> tuple | BaseModelOutput: + all_hidden_states = () if output_hidden_states else None + all_self_attentions = () if output_attentions else None + + batch_size = pixel_values.shape[0] + num_blocks = len(self.block) + hidden_states = pixel_values + for idx, (embedding_layer, block_layer) in enumerate(zip(self.patch_embeddings, self.block)): + # first, obtain patch embeddings + hidden_states, height, width = embedding_layer(hidden_states) + # second, send embeddings through blocks + for block in block_layer: + layer_outputs = block(hidden_states, height, width, output_attentions) + hidden_states = layer_outputs[0] + if output_attentions: + all_self_attentions = all_self_attentions + (layer_outputs[1],) + if output_hidden_states: + all_hidden_states = all_hidden_states + (hidden_states,) + if idx != num_blocks - 1: + hidden_states = hidden_states.reshape(batch_size, height, width, -1).permute(0, 3, 1, 2).contiguous() + hidden_states = self.layer_norm(hidden_states) + if output_hidden_states: + all_hidden_states = all_hidden_states + (hidden_states,) + if not return_dict: + return tuple(v for v in [hidden_states, all_hidden_states, all_self_attentions] if v is not None) + return BaseModelOutput( + last_hidden_state=hidden_states, + hidden_states=all_hidden_states, + attentions=all_self_attentions, + ) + + +@auto_docstring +class PvtPreTrainedModel(PreTrainedModel): + config: PvtConfig + base_model_prefix = "pvt" + main_input_name = "pixel_values" + input_modalities = ("image",) + _no_split_modules = [] + + @torch.no_grad() + def _init_weights(self, module: nn.Module) -> None: + """Initialize the weights""" + std = self.config.initializer_range + if isinstance(module, (nn.Linear, nn.Conv2d)): + init.trunc_normal_(module.weight, mean=0.0, std=std) + if module.bias is not None: + init.zeros_(module.bias) + elif isinstance(module, nn.LayerNorm): + init.zeros_(module.bias) + init.ones_(module.weight) + elif isinstance(module, PvtPatchEmbeddings): + init.trunc_normal_(module.position_embeddings, mean=0.0, std=std) + if module.cls_token is not None: + init.trunc_normal_(module.cls_token, mean=0.0, std=std) + + +@auto_docstring +class PvtModel(PvtPreTrainedModel): + def __init__(self, config: PvtConfig): + super().__init__(config) + self.config = config + + # hierarchical Transformer encoder + self.encoder = PvtEncoder(config) + + # Initialize weights and apply final processing + self.post_init() + + @auto_docstring + def forward( + self, + pixel_values: torch.FloatTensor, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + **kwargs, + ) -> tuple | BaseModelOutput: + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + encoder_outputs = self.encoder( + pixel_values=pixel_values, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + sequence_output = encoder_outputs[0] + + if not return_dict: + return (sequence_output,) + encoder_outputs[1:] + + return BaseModelOutput( + last_hidden_state=sequence_output, + hidden_states=encoder_outputs.hidden_states, + attentions=encoder_outputs.attentions, + ) + + +@auto_docstring( + custom_intro=""" + Pvt Model transformer with an image classification head on top (a linear layer on top of the final hidden state of + the [CLS] token) e.g. for ImageNet. + """ +) +class PvtForImageClassification(PvtPreTrainedModel): + def __init__(self, config: PvtConfig) -> None: + super().__init__(config) + + self.num_labels = config.num_labels + self.pvt = PvtModel(config) + + # Classifier head + self.classifier = ( + nn.Linear(config.hidden_sizes[-1], config.num_labels) if config.num_labels > 0 else nn.Identity() + ) + + # Initialize weights and apply final processing + self.post_init() + + @auto_docstring + def forward( + self, + pixel_values: torch.Tensor | None, + labels: torch.Tensor | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + **kwargs, + ) -> tuple | ImageClassifierOutput: + r""" + labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*): + Labels for computing the image classification/regression loss. Indices should be in `[0, ..., + config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If + `config.num_labels > 1` a classification loss is computed (Cross-Entropy). + """ + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + outputs = self.pvt( + pixel_values=pixel_values, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + + sequence_output = outputs[0] + + logits = self.classifier(sequence_output[:, 0, :]) + + loss = None + if labels is not None: + loss = self.loss_function(labels, logits, self.config) + + if not return_dict: + output = (logits,) + outputs[1:] + return ((loss,) + output) if loss is not None else output + + return ImageClassifierOutput( + loss=loss, + logits=logits, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + ) + + +__all__ = ["PvtForImageClassification", "PvtModel", "PvtPreTrainedModel"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pvt_v2/__init__.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pvt_v2/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..e3cb83f130dd42eb08943d5d4e08ed9321e6f076 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pvt_v2/__init__.py @@ -0,0 +1,27 @@ +# Copyright 2024 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from typing import TYPE_CHECKING + +from ...utils import _LazyModule +from ...utils.import_utils import define_import_structure + + +if TYPE_CHECKING: + from .configuration_pvt_v2 import * + from .modeling_pvt_v2 import * +else: + import sys + + _file = globals()["__file__"] + sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__) diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pvt_v2/configuration_pvt_v2.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pvt_v2/configuration_pvt_v2.py new file mode 100644 index 0000000000000000000000000000000000000000..a87567fbdb0932aad4579711f0c0e4207cd00967 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pvt_v2/configuration_pvt_v2.py @@ -0,0 +1,153 @@ +# Copyright 2024 Authors: Wenhai Wang, Enze Xie, Xiang Li, Deng-Ping Fan, +# Kaitao Song, Ding Liang, Tong Lu, Ping Luo, Ling Shao and The HuggingFace Inc. team. +# All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""Pvt V2 model configuration""" + +from collections.abc import Callable + +from ...backbone_utils import BackboneConfigMixin +from ...configuration_utils import PreTrainedConfig +from ...utils import logging + + +logger = logging.get_logger(__name__) + + +class PvtV2Config(BackboneConfigMixin, PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`PvtV2Model`]. It is used to instantiate a Pvt V2 + model according to the specified arguments, defining the model architecture. Instantiating a configuration with the + defaults will yield a similar configuration to that of the Pvt V2 B0 + [OpenGVLab/pvt_v2_b0](https://huggingface.co/OpenGVLab/pvt_v2_b0) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + image_size (`Union[int, tuple[int, int]]`, *optional*, defaults to 224): + The input image size. Pass int value for square image, or tuple of (height, width). + num_channels (`int`, *optional*, defaults to 3): + The number of input channels. + num_encoder_blocks (`[int]`, *optional*, defaults to 4): + The number of encoder blocks (i.e. stages in the Mix Transformer encoder). + depths (`list[int]`, *optional*, defaults to `[2, 2, 2, 2]`): + The number of layers in each encoder block. + sr_ratios (`list[int]`, *optional*, defaults to `[8, 4, 2, 1]`): + Spatial reduction ratios in each encoder block. + hidden_sizes (`list[int]`, *optional*, defaults to `[32, 64, 160, 256]`): + Dimension of each of the encoder blocks. + patch_sizes (`list[int]`, *optional*, defaults to `[7, 3, 3, 3]`): + Patch size for overlapping patch embedding before each encoder block. + strides (`list[int]`, *optional*, defaults to `[4, 2, 2, 2]`): + Stride for overlapping patch embedding before each encoder block. + num_attention_heads (`list[int]`, *optional*, defaults to `[1, 2, 5, 8]`): + Number of attention heads for each attention layer in each block of the Transformer encoder. + mlp_ratios (`list[int]`, *optional*, defaults to `[8, 8, 4, 4]`): + Ratio of the size of the hidden layer compared to the size of the input layer of the Mix FFNs in the + encoder blocks. + hidden_act (`str` or `Callable`, *optional*, defaults to `"gelu"`): + The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`, + `"relu"`, `"selu"` and `"gelu_new"` are supported. + hidden_dropout_prob (`float`, *optional*, defaults to 0.0): + The dropout probability for all fully connected layers in the embeddings, encoder, and pooler. + attention_probs_dropout_prob (`float`, *optional*, defaults to 0.0): + The dropout ratio for the attention probabilities. + initializer_range (`float`, *optional*, defaults to 0.02): + The standard deviation of the truncated_normal_initializer for initializing all weight matrices. + drop_path_rate (`float`, *optional*, defaults to 0.0): + The dropout probability for stochastic depth, used in the blocks of the Transformer encoder. + layer_norm_eps (`float`, *optional*, defaults to 1e-06): + The epsilon used by the layer normalization layers. + qkv_bias (`bool`, *optional*, defaults to `True`): + Whether or not a learnable bias should be added to the queries, keys and values. + linear_attention (`bool`, *optional*, defaults to `False`): + Use linear attention complexity. If set to True, `sr_ratio` is ignored and average pooling is used for + dimensionality reduction in the attention layers rather than strided convolution. + out_features (`list[str]`, *optional*): + If used as backbone, list of features to output. Can be any of `"stem"`, `"stage1"`, `"stage2"`, etc. + (depending on how many stages the model has). If unset and `out_indices` is set, will default to the + corresponding stages. If unset and `out_indices` is unset, will default to the last stage. + out_indices (`list[int]`, *optional*): + If used as backbone, list of indices of features to output. Can be any of 0, 1, 2, etc. (depending on how + many stages the model has). If unset and `out_features` is set, will default to the corresponding stages. + If unset and `out_features` is unset, will default to the last stage. + Example: + + ```python + >>> from transformers import PvtV2Model, PvtV2Config + + >>> # Initializing a pvt_v2_b0 style configuration + >>> configuration = PvtV2Config() + + >>> # Initializing a model from the OpenGVLab/pvt_v2_b0 style configuration + >>> model = PvtV2Model(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "pvt_v2" + + def __init__( + self, + image_size: int | tuple[int, int] = 224, + num_channels: int = 3, + num_encoder_blocks: int = 4, + depths: list[int] = [2, 2, 2, 2], + sr_ratios: list[int] = [8, 4, 2, 1], + hidden_sizes: list[int] = [32, 64, 160, 256], + patch_sizes: list[int] = [7, 3, 3, 3], + strides: list[int] = [4, 2, 2, 2], + num_attention_heads: list[int] = [1, 2, 5, 8], + mlp_ratios: list[int] = [8, 8, 4, 4], + hidden_act: str | Callable = "gelu", + hidden_dropout_prob: float = 0.0, + attention_probs_dropout_prob: float = 0.0, + initializer_range: float = 0.02, + drop_path_rate: float = 0.0, + layer_norm_eps: float = 1e-6, + qkv_bias: bool = True, + linear_attention: bool = False, + out_features=None, + out_indices=None, + **kwargs, + ): + super().__init__(**kwargs) + + image_size = (image_size, image_size) if isinstance(image_size, int) else image_size + + self.image_size = image_size + self.num_channels = num_channels + self.num_encoder_blocks = num_encoder_blocks + self.depths = depths + self.sr_ratios = sr_ratios + self.hidden_sizes = hidden_sizes + self.patch_sizes = patch_sizes + self.strides = strides + self.mlp_ratios = mlp_ratios + self.num_attention_heads = num_attention_heads + self.hidden_act = hidden_act + self.hidden_dropout_prob = hidden_dropout_prob + self.attention_probs_dropout_prob = attention_probs_dropout_prob + self.initializer_range = initializer_range + self.drop_path_rate = drop_path_rate + self.layer_norm_eps = layer_norm_eps + self.qkv_bias = qkv_bias + self.linear_attention = linear_attention + self.stage_names = [f"stage{idx}" for idx in range(1, len(depths) + 1)] + self.set_output_features_output_indices(out_indices=out_indices, out_features=out_features) + + +__all__ = ["PvtV2Config"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pvt_v2/modeling_pvt_v2.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pvt_v2/modeling_pvt_v2.py new file mode 100644 index 0000000000000000000000000000000000000000..39a2d6cc3bc2dc3a50d9c2663299cd1afb02e37f --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/pvt_v2/modeling_pvt_v2.py @@ -0,0 +1,585 @@ +# Copyright 2024 Authors: Wenhai Wang, Enze Xie, Xiang Li, Deng-Ping Fan, +# Kaitao Song, Ding Liang, Tong Lu, Ping Luo, Ling Shao and The HuggingFace Inc. team. +# All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""PyTorch PVTv2 model.""" + +import math + +import torch +from torch import nn + +from ... import initialization as init +from ...activations import ACT2FN +from ...backbone_utils import BackboneMixin +from ...modeling_layers import GradientCheckpointingLayer +from ...modeling_outputs import BackboneOutput, BaseModelOutput, ImageClassifierOutput +from ...modeling_utils import PreTrainedModel +from ...utils import auto_docstring, logging +from .configuration_pvt_v2 import PvtV2Config + + +logger = logging.get_logger(__name__) + + +# Copied from transformers.models.beit.modeling_beit.drop_path +def drop_path(input: torch.Tensor, drop_prob: float = 0.0, training: bool = False) -> torch.Tensor: + """ + Drop paths (Stochastic Depth) per sample (when applied in main path of residual blocks). + + """ + if drop_prob == 0.0 or not training: + return input + keep_prob = 1 - drop_prob + shape = (input.shape[0],) + (1,) * (input.ndim - 1) # work with diff dim tensors, not just 2D ConvNets + random_tensor = keep_prob + torch.rand(shape, dtype=input.dtype, device=input.device) + random_tensor.floor_() # binarize + output = input.div(keep_prob) * random_tensor + return output + + +# Copied from transformers.models.convnext.modeling_convnext.ConvNextDropPath with ConvNext->Pvt +class PvtV2DropPath(nn.Module): + """Drop paths (Stochastic Depth) per sample (when applied in main path of residual blocks).""" + + def __init__(self, drop_prob: float | None = None) -> None: + super().__init__() + self.drop_prob = drop_prob + + def forward(self, hidden_states: torch.Tensor) -> torch.Tensor: + return drop_path(hidden_states, self.drop_prob, self.training) + + def extra_repr(self) -> str: + return f"p={self.drop_prob}" + + +class PvtV2OverlapPatchEmbeddings(nn.Module): + """Image to Patch Embedding""" + + def __init__(self, config: PvtV2Config, layer_idx: int): + super().__init__() + patch_size = config.patch_sizes[layer_idx] + patch_size = (patch_size, patch_size) if isinstance(patch_size, int) else patch_size + stride = config.strides[layer_idx] + num_channels = config.num_channels if layer_idx == 0 else config.hidden_sizes[layer_idx - 1] + hidden_size = config.hidden_sizes[layer_idx] + self.patch_size = patch_size + self.proj = nn.Conv2d( + num_channels, + hidden_size, + kernel_size=patch_size, + stride=stride, + padding=(patch_size[0] // 2, patch_size[1] // 2), + ) + self.layer_norm = nn.LayerNorm(hidden_size, eps=config.layer_norm_eps) + + def forward(self, pixel_values): + embeddings = self.proj(pixel_values) + _, _, height, width = embeddings.shape + embeddings = embeddings.flatten(2).transpose(1, 2) + embeddings = self.layer_norm(embeddings) + return embeddings, height, width + + +class PvtV2DepthWiseConv(nn.Module): + """ + Depth-wise (DW) convolution to infuse positional information using zero-padding. Depth-wise convolutions + have an equal number of groups to the number of input channels, meaning one filter per input channel. This + reduces the overall parameters and compute costs since the key purpose of this layer is position encoding. + """ + + def __init__(self, config: PvtV2Config, dim: int = 768): + super().__init__() + self.dwconv = nn.Conv2d(dim, dim, 3, 1, 1, bias=True, groups=dim) + + def forward(self, hidden_states, height, width): + batch_size, seq_len, num_channels = hidden_states.shape + hidden_states = hidden_states.transpose(1, 2).view(batch_size, num_channels, height, width) + hidden_states = self.dwconv(hidden_states) + hidden_states = hidden_states.flatten(2).transpose(1, 2) + + return hidden_states + + +class PvtV2SelfAttention(nn.Module): + """Efficient self-attention mechanism.""" + + def __init__(self, config: PvtV2Config, hidden_size: int, num_attention_heads: int, spatial_reduction_ratio: int): + super().__init__() + self.linear_attention = config.linear_attention + + self.hidden_size = hidden_size + self.num_attention_heads = num_attention_heads + + if self.hidden_size % self.num_attention_heads != 0: + raise ValueError( + f"The hidden size ({self.hidden_size}) is not a multiple of the number of attention " + f"heads ({self.num_attention_heads})" + ) + + self.attention_head_size = int(self.hidden_size / self.num_attention_heads) + self.all_head_size = self.num_attention_heads * self.attention_head_size + + self.query = nn.Linear(self.hidden_size, self.all_head_size, bias=config.qkv_bias) + self.key = nn.Linear(self.hidden_size, self.all_head_size, bias=config.qkv_bias) + self.value = nn.Linear(self.hidden_size, self.all_head_size, bias=config.qkv_bias) + self.attn_drop = nn.Dropout(config.attention_probs_dropout_prob) + self.proj = nn.Linear(self.hidden_size, self.hidden_size) + self.proj_drop = nn.Dropout(config.hidden_dropout_prob) + + self.spatial_reduction_ratio = spatial_reduction_ratio + if self.linear_attention: + self.pool = nn.AdaptiveAvgPool2d(7) + self.spatial_reduction = nn.Conv2d(self.hidden_size, self.hidden_size, kernel_size=1, stride=1) + self.layer_norm = nn.LayerNorm(self.hidden_size, eps=config.layer_norm_eps) + self.act = nn.GELU() + elif spatial_reduction_ratio > 1: + self.spatial_reduction = nn.Conv2d( + self.hidden_size, self.hidden_size, kernel_size=spatial_reduction_ratio, stride=spatial_reduction_ratio + ) + self.layer_norm = nn.LayerNorm(self.hidden_size, eps=config.layer_norm_eps) + + def transpose_for_scores(self, hidden_states) -> torch.Tensor: + new_shape = hidden_states.size()[:-1] + (self.num_attention_heads, self.attention_head_size) + hidden_states = hidden_states.view(new_shape) + return hidden_states.permute(0, 2, 1, 3) + + def forward( + self, + hidden_states: torch.Tensor, + height: int, + width: int, + output_attentions: bool = False, + ) -> tuple[torch.Tensor]: + batch_size, seq_len, num_channels = hidden_states.shape + query_layer = self.transpose_for_scores(self.query(hidden_states)) + + if self.linear_attention: + hidden_states = hidden_states.permute(0, 2, 1).reshape(batch_size, num_channels, height, width) + hidden_states = ( + self.spatial_reduction(self.pool(hidden_states)).reshape(batch_size, num_channels, -1).permute(0, 2, 1) + ) + hidden_states = self.act(self.layer_norm(hidden_states)) + elif self.spatial_reduction_ratio > 1: + hidden_states = hidden_states.permute(0, 2, 1).reshape(batch_size, num_channels, height, width) + hidden_states = ( + self.spatial_reduction(hidden_states).reshape(batch_size, num_channels, -1).permute(0, 2, 1) + ) + hidden_states = self.layer_norm(hidden_states) + + key_layer = self.transpose_for_scores(self.key(hidden_states)) + value_layer = self.transpose_for_scores(self.value(hidden_states)) + + # Take the dot product between "query" and "key" to get the raw attention scores. + attention_scores = torch.matmul(query_layer, key_layer.transpose(-1, -2)) + + attention_scores = attention_scores / math.sqrt(self.attention_head_size) + + # Normalize the attention scores to probabilities. + attention_probs = nn.functional.softmax(attention_scores, dim=-1) + + # This is actually dropping out entire tokens to attend to, which might + # seem a bit unusual, but is taken from the original Transformer paper. + attention_probs = self.attn_drop(attention_probs) + context_layer = (attention_probs @ value_layer).transpose(1, 2).reshape(batch_size, seq_len, num_channels) + context_layer = self.proj(context_layer) + context_layer = self.proj_drop(context_layer) + + outputs = (context_layer, attention_probs) if output_attentions else (context_layer,) + + return outputs + + +class PvtV2ConvFeedForwardNetwork(nn.Module): + def __init__( + self, + config: PvtV2Config, + in_features: int, + hidden_features: int | None = None, + out_features: int | None = None, + ): + super().__init__() + out_features = out_features if out_features is not None else in_features + self.dense1 = nn.Linear(in_features, hidden_features) + self.dwconv = PvtV2DepthWiseConv(config, hidden_features) + if isinstance(config.hidden_act, str): + self.intermediate_act_fn = ACT2FN[config.hidden_act] + else: + self.intermediate_act_fn = config.hidden_act + self.dense2 = nn.Linear(hidden_features, out_features) + self.dropout = nn.Dropout(config.hidden_dropout_prob) + self.relu = nn.ReLU() if config.linear_attention else nn.Identity() + + def forward(self, hidden_states: torch.Tensor, height, width) -> torch.Tensor: + hidden_states = self.dense1(hidden_states) + hidden_states = self.relu(hidden_states) + hidden_states = self.dwconv(hidden_states, height, width) + hidden_states = self.intermediate_act_fn(hidden_states) + hidden_states = self.dropout(hidden_states) + hidden_states = self.dense2(hidden_states) + hidden_states = self.dropout(hidden_states) + return hidden_states + + +class PvtV2BlockLayer(nn.Module): + def __init__(self, config: PvtV2Config, layer_idx: int, drop_path: float = 0.0): + super().__init__() + hidden_size: int = config.hidden_sizes[layer_idx] + num_attention_heads: int = config.num_attention_heads[layer_idx] + spatial_reduction_ratio: int = config.sr_ratios[layer_idx] + mlp_ratio: float = config.mlp_ratios[layer_idx] + self.layer_norm_1 = nn.LayerNorm(hidden_size, eps=config.layer_norm_eps) + self.attention = PvtV2SelfAttention( + config=config, + hidden_size=hidden_size, + num_attention_heads=num_attention_heads, + spatial_reduction_ratio=spatial_reduction_ratio, + ) + self.drop_path = PvtV2DropPath(drop_path) if drop_path > 0.0 else nn.Identity() + self.layer_norm_2 = nn.LayerNorm(hidden_size, eps=config.layer_norm_eps) + mlp_hidden_size = int(hidden_size * mlp_ratio) + self.mlp = PvtV2ConvFeedForwardNetwork(config=config, in_features=hidden_size, hidden_features=mlp_hidden_size) + + def forward(self, hidden_states: torch.Tensor, height: int, width: int, output_attentions: bool = False): + self_attention_outputs = self.attention( + hidden_states=self.layer_norm_1(hidden_states), + height=height, + width=width, + output_attentions=output_attentions, + ) + attention_output = self_attention_outputs[0] + outputs = self_attention_outputs[1:] + + attention_output = self.drop_path(attention_output) + hidden_states = attention_output + hidden_states + + mlp_output = self.mlp(self.layer_norm_2(hidden_states), height, width) + + mlp_output = self.drop_path(mlp_output) + layer_output = hidden_states + mlp_output + + outputs = (layer_output,) + outputs + + return outputs + + +class PvtV2EncoderLayer(GradientCheckpointingLayer): + def __init__(self, config: PvtV2Config, layer_idx: int): + super().__init__() + self.patch_embedding = PvtV2OverlapPatchEmbeddings( + config=config, + layer_idx=layer_idx, + ) + # Transformer block + # stochastic depth decay rule + drop_path_decays = torch.linspace(0, config.drop_path_rate, sum(config.depths), device="cpu").tolist() + block_layers = [] + for block_idx in range(config.depths[layer_idx]): + block_layers.append( + PvtV2BlockLayer( + config=config, + layer_idx=layer_idx, + drop_path=drop_path_decays[sum(config.depths[:layer_idx]) + block_idx], + ) + ) + self.blocks = nn.ModuleList(block_layers) + + # Layer norm + self.layer_norm = nn.LayerNorm(config.hidden_sizes[layer_idx], eps=config.layer_norm_eps) + + def forward(self, hidden_states, output_attentions): + all_self_attentions = () if output_attentions else None + # first, obtain patch embeddings + hidden_states, height, width = self.patch_embedding(hidden_states) + # second, send embeddings through blocks + for block in self.blocks: + layer_outputs = block(hidden_states, height, width, output_attentions) + hidden_states = layer_outputs[0] + if output_attentions: + all_self_attentions += (layer_outputs[1],) + # third, apply layer norm + hidden_states = self.layer_norm(hidden_states) + + outputs = (hidden_states,) + + if output_attentions: + outputs += (all_self_attentions,) + + return outputs, height, width + + +class PvtV2Encoder(nn.Module): + def __init__(self, config: PvtV2Config): + super().__init__() + self.config = config + self.gradient_checkpointing = False + + # encoder layers + self.layers = nn.ModuleList([PvtV2EncoderLayer(config, i) for i in range(config.num_encoder_blocks)]) + + def forward( + self, + pixel_values: torch.FloatTensor, + output_attentions: bool | None = False, + output_hidden_states: bool | None = False, + return_dict: bool | None = True, + ) -> tuple | BaseModelOutput: + all_hidden_states = () if output_hidden_states else None + all_self_attentions = () if output_attentions else None + + batch_size = pixel_values.shape[0] + hidden_states = pixel_values + for idx, layer in enumerate(self.layers): + layer_output = layer(hidden_states, output_attentions) + outputs, height, width = layer_output + hidden_states = outputs[0] + if output_attentions: + all_self_attentions = all_self_attentions + (outputs[1],) + # reshape back to (batch_size, num_channels, height, width) + hidden_states = hidden_states.reshape(batch_size, height, width, -1).permute(0, 3, 1, 2).contiguous() + if output_hidden_states: + all_hidden_states = all_hidden_states + (hidden_states,) + if not return_dict: + return tuple(v for v in [hidden_states, all_hidden_states, all_self_attentions] if v is not None) + return BaseModelOutput( + last_hidden_state=hidden_states, + hidden_states=all_hidden_states, + attentions=all_self_attentions, + ) + + +@auto_docstring +class PvtV2PreTrainedModel(PreTrainedModel): + config: PvtV2Config + base_model_prefix = "pvt_v2" + main_input_name = "pixel_values" + input_modalities = ("image",) + supports_gradient_checkpointing = True + + @torch.no_grad() + def _init_weights(self, module: nn.Linear | nn.Conv2d | nn.LayerNorm) -> None: + """Initialize the weights""" + if isinstance(module, nn.Linear): + init.trunc_normal_(module.weight, mean=0.0, std=self.config.initializer_range) + if module.bias is not None: + init.zeros_(module.bias) + elif isinstance(module, nn.LayerNorm): + init.zeros_(module.bias) + init.ones_(module.weight) + elif isinstance(module, nn.Conv2d): + fan_out = module.kernel_size[0] * module.kernel_size[1] * module.out_channels + fan_out //= module.groups + init.normal_(module.weight, 0, math.sqrt(2.0 / fan_out)) + if module.bias is not None: + init.zeros_(module.bias) + + +@auto_docstring +class PvtV2Model(PvtV2PreTrainedModel): + def __init__(self, config: PvtV2Config): + super().__init__(config) + self.config = config + + # hierarchical Transformer encoder + self.encoder = PvtV2Encoder(config) + + # Initialize weights and apply final processing + self.post_init() + + @auto_docstring + def forward( + self, + pixel_values: torch.FloatTensor, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + **kwargs, + ) -> tuple | BaseModelOutput: + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + encoder_outputs = self.encoder( + pixel_values=pixel_values, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + sequence_output = encoder_outputs[0] + + if not return_dict: + return (sequence_output,) + encoder_outputs[1:] + + return BaseModelOutput( + last_hidden_state=sequence_output, + hidden_states=encoder_outputs.hidden_states, + attentions=encoder_outputs.attentions, + ) + + +@auto_docstring( + custom_intro=""" + Pvt-v2 Model transformer with an image classification head on top (a linear layer on top of the final hidden state + of the [CLS] token) e.g. for ImageNet. + """ +) +class PvtV2ForImageClassification(PvtV2PreTrainedModel): + def __init__(self, config: PvtV2Config) -> None: + super().__init__(config) + + self.num_labels = config.num_labels + self.pvt_v2 = PvtV2Model(config) + + # Classifier head + self.classifier = ( + nn.Linear(config.hidden_sizes[-1], config.num_labels) if config.num_labels > 0 else nn.Identity() + ) + + # Initialize weights and apply final processing + self.post_init() + + @auto_docstring + def forward( + self, + pixel_values: torch.Tensor | None, + labels: torch.Tensor | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + **kwargs, + ) -> tuple | ImageClassifierOutput: + r""" + labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*): + Labels for computing the image classification/regression loss. Indices should be in `[0, ..., + config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If + `config.num_labels > 1` a classification loss is computed (Cross-Entropy). + """ + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + outputs = self.pvt_v2( + pixel_values=pixel_values, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + + sequence_output = outputs[0] + + # convert last hidden states to (batch_size, height*width, hidden_size) + batch_size = sequence_output.shape[0] + # (batch_size, num_channels, height, width) -> (batch_size, height, width, num_channels) + sequence_output = sequence_output.permute(0, 2, 3, 1) + sequence_output = sequence_output.reshape(batch_size, -1, self.config.hidden_sizes[-1]) + + # global average pooling + sequence_output = sequence_output.mean(dim=1) + + logits = self.classifier(sequence_output) + + loss = None + if labels is not None: + loss = self.loss_function(labels, logits, self.config) + + if not return_dict: + output = (logits,) + outputs[1:] + return ((loss,) + output) if loss is not None else output + + return ImageClassifierOutput( + loss=loss, + logits=logits, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + ) + + +@auto_docstring( + custom_intro=""" + PVTv2 backbone, to be used with frameworks like DETR and MaskFormer. + """ +) +class PvtV2Backbone(BackboneMixin, PvtV2Model): + def __init__(self, config: PvtV2Config): + super().__init__(config) + self.num_features = config.hidden_sizes + + @auto_docstring + def forward( + self, + pixel_values: torch.FloatTensor, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + **kwargs, + ) -> BackboneOutput: + r""" + Examples: + + ```python + >>> from transformers import AutoImageProcessor, AutoBackbone + >>> import torch + >>> from PIL import Image + >>> import httpx + >>> from io import BytesIO + + >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg" + >>> with httpx.stream("GET", url) as response: + ... image = Image.open(BytesIO(response.read())) + + >>> processor = AutoImageProcessor.from_pretrained("OpenGVLab/pvt_v2_b0") + >>> model = AutoBackbone.from_pretrained( + ... "OpenGVLab/pvt_v2_b0", out_features=["stage1", "stage2", "stage3", "stage4"] + ... ) + + >>> inputs = processor(image, return_tensors="pt") + + >>> outputs = model(**inputs) + >>> feature_maps = outputs.feature_maps + >>> list(feature_maps[-1].shape) + [1, 256, 7, 7] + ```""" + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + + outputs = self.encoder( + pixel_values=pixel_values, + output_attentions=output_attentions, + output_hidden_states=True, + return_dict=return_dict, + ) + + hidden_states = outputs.hidden_states + + feature_maps = () + for idx, stage in enumerate(self.stage_names): + if stage in self.out_features: + feature_maps += (hidden_states[idx],) + + if not return_dict: + output = (feature_maps,) + if output_hidden_states: + output += (outputs.hidden_states,) + return output + + return BackboneOutput( + feature_maps=feature_maps, + hidden_states=outputs.hidden_states if output_hidden_states else None, + attentions=None, + ) + + +__all__ = ["PvtV2ForImageClassification", "PvtV2Model", "PvtV2PreTrainedModel", "PvtV2Backbone"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/qwen2/__init__.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/qwen2/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..e447a94c54c86d07eee6c534a6860a2a5a6d0c3e --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/qwen2/__init__.py @@ -0,0 +1,29 @@ +# Copyright 2024 The Qwen Team and The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from typing import TYPE_CHECKING + +from ...utils import _LazyModule +from ...utils.import_utils import define_import_structure + + +if TYPE_CHECKING: + from .configuration_qwen2 import * + from .modeling_qwen2 import * + from .tokenization_qwen2 import * + from .tokenization_qwen2_fast import * +else: + import sys + + _file = globals()["__file__"] + sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__) diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/qwen2/configuration_qwen2.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/qwen2/configuration_qwen2.py new file mode 100644 index 0000000000000000000000000000000000000000..dc579405c72d959b08a4059353a7ea45a45a1e39 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/qwen2/configuration_qwen2.py @@ -0,0 +1,186 @@ +# Copyright 2024 The Qwen team, Alibaba Group and the HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""Qwen2 model configuration""" + +from ...configuration_utils import PreTrainedConfig, layer_type_validation +from ...modeling_rope_utils import RopeParameters +from ...utils import logging + + +logger = logging.get_logger(__name__) + + +class Qwen2Config(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`Qwen2Model`]. It is used to instantiate a + Qwen2 model according to the specified arguments, defining the model architecture. Instantiating a configuration + with the defaults will yield a similar configuration to that of + Qwen2-7B-beta [Qwen/Qwen2-7B-beta](https://huggingface.co/Qwen/Qwen2-7B-beta). + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + + Args: + vocab_size (`int`, *optional*, defaults to 151936): + Vocabulary size of the Qwen2 model. Defines the number of different tokens that can be represented by the + `inputs_ids` passed when calling [`Qwen2Model`] + hidden_size (`int`, *optional*, defaults to 4096): + Dimension of the hidden representations. + intermediate_size (`int`, *optional*, defaults to 22016): + Dimension of the MLP representations. + num_hidden_layers (`int`, *optional*, defaults to 32): + Number of hidden layers in the Transformer encoder. + num_attention_heads (`int`, *optional*, defaults to 32): + Number of attention heads for each attention layer in the Transformer encoder. + num_key_value_heads (`int`, *optional*, defaults to 32): + This is the number of key_value heads that should be used to implement Grouped Query Attention. If + `num_key_value_heads=num_attention_heads`, the model will use Multi Head Attention (MHA), if + `num_key_value_heads=1` the model will use Multi Query Attention (MQA) otherwise GQA is used. When + converting a multi-head checkpoint to a GQA checkpoint, each group key and value head should be constructed + by meanpooling all the original heads within that group. For more details, check out [this + paper](https://huggingface.co/papers/2305.13245). If it is not specified, will default to `32`. + hidden_act (`str` or `function`, *optional*, defaults to `"silu"`): + The non-linear activation function (function or string) in the decoder. + max_position_embeddings (`int`, *optional*, defaults to 32768): + The maximum sequence length that this model might ever be used with. + initializer_range (`float`, *optional*, defaults to 0.02): + The standard deviation of the truncated_normal_initializer for initializing all weight matrices. + rms_norm_eps (`float`, *optional*, defaults to 1e-06): + The epsilon used by the rms normalization layers. + use_cache (`bool`, *optional*, defaults to `True`): + Whether or not the model should return the last key/values attentions (not used by all models). Only + relevant if `config.is_decoder=True`. + tie_word_embeddings (`bool`, *optional*, defaults to `False`): + Whether the model's input and output word embeddings should be tied. + rope_parameters (`RopeParameters`, *optional*): + Dictionary containing the configuration parameters for the RoPE embeddings. The dictionary should contain + a value for `rope_theta` and optionally parameters used for scaling in case you want to use RoPE + with longer `max_position_embeddings`. + use_sliding_window (`bool`, *optional*, defaults to `False`): + Whether to use sliding window attention. + sliding_window (`int`, *optional*, defaults to 4096): + Sliding window attention (SWA) window size. If not specified, will default to `4096`. + max_window_layers (`int`, *optional*, defaults to 28): + The number of layers using full attention. The first `max_window_layers` layers will use full attention, while any + additional layer afterwards will use SWA (Sliding Window Attention). + layer_types (`list`, *optional*): + Attention pattern for each layer. + attention_dropout (`float`, *optional*, defaults to 0.0): + The dropout ratio for the attention probabilities. + pad_token_id (`int`, *optional*): + Padding token id. + bos_token_id (`int`, *optional*): + Beginning of stream token id. + eos_token_id (`int`, *optional*): + End of stream token id. + + ```python + >>> from transformers import Qwen2Model, Qwen2Config + + >>> # Initializing a Qwen2 style configuration + >>> configuration = Qwen2Config() + + >>> # Initializing a model from the Qwen2-7B style configuration + >>> model = Qwen2Model(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "qwen2" + keys_to_ignore_at_inference = ["past_key_values"] + + # Default tensor parallel plan for base model `Qwen2` + base_model_tp_plan = { + "layers.*.self_attn.q_proj": "colwise", + "layers.*.self_attn.k_proj": "colwise", + "layers.*.self_attn.v_proj": "colwise", + "layers.*.self_attn.o_proj": "rowwise", + "layers.*.mlp.gate_proj": "colwise", + "layers.*.mlp.up_proj": "colwise", + "layers.*.mlp.down_proj": "rowwise", + } + base_model_pp_plan = { + "embed_tokens": (["input_ids"], ["inputs_embeds"]), + "layers": (["hidden_states", "attention_mask"], ["hidden_states"]), + "norm": (["hidden_states"], ["hidden_states"]), + } + + def __init__( + self, + vocab_size: int | None = 151936, + hidden_size: int | None = 4096, + intermediate_size: int | None = 22016, + num_hidden_layers: int | None = 32, + num_attention_heads: int | None = 32, + num_key_value_heads: int | None = 32, + hidden_act: str | None = "silu", + max_position_embeddings: int | None = 32768, + initializer_range: float | None = 0.02, + rms_norm_eps: int | None = 1e-6, + use_cache: bool | None = True, + tie_word_embeddings: bool | None = False, + rope_parameters: RopeParameters | dict[str, RopeParameters] | None = None, + use_sliding_window: bool | None = False, + sliding_window: int | None = 4096, + max_window_layers: int | None = 28, + layer_types: list[str] | None = None, + attention_dropout: float | None = 0.0, + pad_token_id: int | None = None, + bos_token_id: int | None = None, + eos_token_id: int | None = None, + **kwargs, + ): + self.vocab_size = vocab_size + self.max_position_embeddings = max_position_embeddings + self.hidden_size = hidden_size + self.intermediate_size = intermediate_size + self.num_hidden_layers = num_hidden_layers + self.num_attention_heads = num_attention_heads + self.use_sliding_window = use_sliding_window + self.sliding_window = sliding_window if self.use_sliding_window else None + self.max_window_layers = max_window_layers + + # for backward compatibility + if num_key_value_heads is None: + num_key_value_heads = num_attention_heads + + self.num_key_value_heads = num_key_value_heads + self.hidden_act = hidden_act + self.initializer_range = initializer_range + self.rms_norm_eps = rms_norm_eps + self.use_cache = use_cache + self.attention_dropout = attention_dropout + + self.layer_types = layer_types + if self.layer_types is None: + self.layer_types = [ + "sliding_attention" + if self.sliding_window is not None and i >= self.max_window_layers + else "full_attention" + for i in range(self.num_hidden_layers) + ] + layer_type_validation(self.layer_types, self.num_hidden_layers) + + self.pad_token_id = pad_token_id + self.bos_token_id = bos_token_id + self.eos_token_id = eos_token_id + self.tie_word_embeddings = tie_word_embeddings + self.rope_parameters = rope_parameters + + super().__init__(**kwargs) + + +__all__ = ["Qwen2Config"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/qwen2/modeling_qwen2.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/qwen2/modeling_qwen2.py new file mode 100644 index 0000000000000000000000000000000000000000..8c55adfa5db6f77afbfcdd28838996748882463f --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/qwen2/modeling_qwen2.py @@ -0,0 +1,525 @@ +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# This file was automatically generated from src/transformers/models/qwen2/modular_qwen2.py. +# Do NOT edit this file manually as any edits will be overwritten by the generation of +# the file from the modular. If any change should be done, please apply the change to the +# modular_qwen2.py file directly. One of our CI enforces this. +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +from collections.abc import Callable +from typing import Optional + +import torch +from torch import nn + +from ...activations import ACT2FN +from ...cache_utils import Cache, DynamicCache +from ...generation import GenerationMixin +from ...integrations import use_kernel_forward_from_hub, use_kernel_func_from_hub, use_kernelized_func +from ...masking_utils import create_causal_mask, create_sliding_window_causal_mask +from ...modeling_flash_attention_utils import FlashAttentionKwargs +from ...modeling_layers import ( + GenericForQuestionAnswering, + GenericForSequenceClassification, + GenericForTokenClassification, + GradientCheckpointingLayer, +) +from ...modeling_outputs import BaseModelOutputWithPast, CausalLMOutputWithPast +from ...modeling_rope_utils import ROPE_INIT_FUNCTIONS, dynamic_rope_update +from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel +from ...processing_utils import Unpack +from ...utils import TransformersKwargs, auto_docstring, can_return_tuple +from ...utils.generic import maybe_autocast, merge_with_config_defaults +from ...utils.output_capturing import capture_outputs +from .configuration_qwen2 import Qwen2Config + + +class Qwen2MLP(nn.Module): + def __init__(self, config): + super().__init__() + self.config = config + self.hidden_size = config.hidden_size + self.intermediate_size = config.intermediate_size + self.gate_proj = nn.Linear(self.hidden_size, self.intermediate_size, bias=False) + self.up_proj = nn.Linear(self.hidden_size, self.intermediate_size, bias=False) + self.down_proj = nn.Linear(self.intermediate_size, self.hidden_size, bias=False) + self.act_fn = ACT2FN[config.hidden_act] + + def forward(self, x): + down_proj = self.down_proj(self.act_fn(self.gate_proj(x)) * self.up_proj(x)) + return down_proj + + +class Qwen2RotaryEmbedding(nn.Module): + inv_freq: torch.Tensor # fix linting for `register_buffer` + + def __init__(self, config: Qwen2Config, device=None): + super().__init__() + self.max_seq_len_cached = config.max_position_embeddings + self.original_max_seq_len = config.max_position_embeddings + + self.config = config + + self.rope_type = self.config.rope_parameters["rope_type"] + rope_init_fn: Callable = self.compute_default_rope_parameters + if self.rope_type != "default": + rope_init_fn = ROPE_INIT_FUNCTIONS[self.rope_type] + inv_freq, self.attention_scaling = rope_init_fn(self.config, device) + + self.register_buffer("inv_freq", inv_freq, persistent=False) + self.register_buffer("original_inv_freq", inv_freq.clone(), persistent=False) + + @staticmethod + def compute_default_rope_parameters( + config: Qwen2Config | None = None, + device: Optional["torch.device"] = None, + seq_len: int | None = None, + ) -> tuple["torch.Tensor", float]: + """ + Computes the inverse frequencies according to the original RoPE implementation + Args: + config ([`~transformers.PreTrainedConfig`]): + The model configuration. + device (`torch.device`): + The device to use for initialization of the inverse frequencies. + seq_len (`int`, *optional*): + The current sequence length. Unused for this type of RoPE. + Returns: + Tuple of (`torch.Tensor`, `float`), containing the inverse frequencies for the RoPE embeddings and the + post-processing scaling factor applied to the computed cos/sin (unused in this type of RoPE). + """ + base = config.rope_parameters["rope_theta"] + dim = getattr(config, "head_dim", None) or config.hidden_size // config.num_attention_heads + + attention_factor = 1.0 # Unused in this type of RoPE + + # Compute the inverse frequencies + inv_freq = 1.0 / ( + base ** (torch.arange(0, dim, 2, dtype=torch.int64).to(device=device, dtype=torch.float) / dim) + ) + return inv_freq, attention_factor + + @torch.no_grad() + @dynamic_rope_update # power user: used with advanced RoPE types (e.g. dynamic rope) + def forward(self, x, position_ids): + inv_freq_expanded = self.inv_freq[None, :, None].float().expand(position_ids.shape[0], -1, 1).to(x.device) + position_ids_expanded = position_ids[:, None, :].float() + + device_type = x.device.type if isinstance(x.device.type, str) and x.device.type != "mps" else "cpu" + with maybe_autocast(device_type=device_type, enabled=False): # Force float32 + freqs = (inv_freq_expanded.float() @ position_ids_expanded.float()).transpose(1, 2) + emb = torch.cat((freqs, freqs), dim=-1) + cos = emb.cos() * self.attention_scaling + sin = emb.sin() * self.attention_scaling + + return cos.to(dtype=x.dtype), sin.to(dtype=x.dtype) + + +def rotate_half(x): + """Rotates half the hidden dims of the input.""" + x1 = x[..., : x.shape[-1] // 2] + x2 = x[..., x.shape[-1] // 2 :] + return torch.cat((-x2, x1), dim=-1) + + +@use_kernel_func_from_hub("rotary_pos_emb") +def apply_rotary_pos_emb(q, k, cos, sin, unsqueeze_dim=1): + """Applies Rotary Position Embedding to the query and key tensors. + + Args: + q (`torch.Tensor`): The query tensor. + k (`torch.Tensor`): The key tensor. + cos (`torch.Tensor`): The cosine part of the rotary embedding. + sin (`torch.Tensor`): The sine part of the rotary embedding. + unsqueeze_dim (`int`, *optional*, defaults to 1): + The 'unsqueeze_dim' argument specifies the dimension along which to unsqueeze cos[position_ids] and + sin[position_ids] so that they can be properly broadcasted to the dimensions of q and k. For example, note + that cos[position_ids] and sin[position_ids] have the shape [batch_size, seq_len, head_dim]. Then, if q and + k have the shape [batch_size, heads, seq_len, head_dim], then setting unsqueeze_dim=1 makes + cos[position_ids] and sin[position_ids] broadcastable to the shapes of q and k. Similarly, if q and k have + the shape [batch_size, seq_len, heads, head_dim], then set unsqueeze_dim=2. + Returns: + `tuple(torch.Tensor)` comprising of the query and key tensors rotated using the Rotary Position Embedding. + """ + cos = cos.unsqueeze(unsqueeze_dim) + sin = sin.unsqueeze(unsqueeze_dim) + q_embed = (q * cos) + (rotate_half(q) * sin) + k_embed = (k * cos) + (rotate_half(k) * sin) + return q_embed, k_embed + + +def repeat_kv(hidden_states: torch.Tensor, n_rep: int) -> torch.Tensor: + """ + This is the equivalent of torch.repeat_interleave(x, dim=1, repeats=n_rep). The hidden states go from (batch, + num_key_value_heads, seqlen, head_dim) to (batch, num_attention_heads, seqlen, head_dim) + """ + batch, num_key_value_heads, slen, head_dim = hidden_states.shape + if n_rep == 1: + return hidden_states + hidden_states = hidden_states[:, :, None, :, :].expand(batch, num_key_value_heads, n_rep, slen, head_dim) + return hidden_states.reshape(batch, num_key_value_heads * n_rep, slen, head_dim) + + +def eager_attention_forward( + module: nn.Module, + query: torch.Tensor, + key: torch.Tensor, + value: torch.Tensor, + attention_mask: torch.Tensor | None, + scaling: float, + dropout: float = 0.0, + **kwargs: Unpack[TransformersKwargs], +): + key_states = repeat_kv(key, module.num_key_value_groups) + value_states = repeat_kv(value, module.num_key_value_groups) + + attn_weights = torch.matmul(query, key_states.transpose(2, 3)) * scaling + if attention_mask is not None: + attn_weights = attn_weights + attention_mask + + attn_weights = nn.functional.softmax(attn_weights, dim=-1, dtype=torch.float32).to(query.dtype) + attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training) + attn_output = torch.matmul(attn_weights, value_states) + attn_output = attn_output.transpose(1, 2).contiguous() + + return attn_output, attn_weights + + +@use_kernelized_func(apply_rotary_pos_emb) +class Qwen2Attention(nn.Module): + """Multi-headed attention from 'Attention Is All You Need' paper""" + + def __init__(self, config: Qwen2Config, layer_idx: int): + super().__init__() + self.layer_type = config.layer_types[layer_idx] if hasattr(config, "layer_types") else None + self.config = config + self.layer_idx = layer_idx + self.head_dim = getattr(config, "head_dim", config.hidden_size // config.num_attention_heads) + self.num_key_value_groups = config.num_attention_heads // config.num_key_value_heads + self.scaling = self.head_dim**-0.5 + self.attention_dropout = config.attention_dropout + self.is_causal = True + self.q_proj = nn.Linear(config.hidden_size, config.num_attention_heads * self.head_dim, bias=True) + self.k_proj = nn.Linear(config.hidden_size, config.num_key_value_heads * self.head_dim, bias=True) + self.v_proj = nn.Linear(config.hidden_size, config.num_key_value_heads * self.head_dim, bias=True) + self.o_proj = nn.Linear(config.num_attention_heads * self.head_dim, config.hidden_size, bias=False) + self.sliding_window = config.sliding_window if self.layer_type == "sliding_attention" else None + + def forward( + self, + hidden_states: torch.Tensor, + position_embeddings: tuple[torch.Tensor, torch.Tensor], + attention_mask: torch.Tensor | None, + past_key_values: Cache | None = None, + cache_position: torch.LongTensor | None = None, + **kwargs: Unpack[FlashAttentionKwargs], + ) -> tuple[torch.Tensor, torch.Tensor | None]: + input_shape = hidden_states.shape[:-1] + hidden_shape = (*input_shape, -1, self.head_dim) + + query_states = self.q_proj(hidden_states).view(hidden_shape).transpose(1, 2) + key_states = self.k_proj(hidden_states).view(hidden_shape).transpose(1, 2) + value_states = self.v_proj(hidden_states).view(hidden_shape).transpose(1, 2) + + cos, sin = position_embeddings + query_states, key_states = apply_rotary_pos_emb(query_states, key_states, cos, sin) + + if past_key_values is not None: + # sin and cos are specific to RoPE models; cache_position needed for the static cache + cache_kwargs = {"sin": sin, "cos": cos, "cache_position": cache_position} + key_states, value_states = past_key_values.update(key_states, value_states, self.layer_idx, cache_kwargs) + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, eager_attention_forward + ) + + attn_output, attn_weights = attention_interface( + self, + query_states, + key_states, + value_states, + attention_mask, + dropout=0.0 if not self.training else self.attention_dropout, + scaling=self.scaling, + sliding_window=self.sliding_window, # main diff with Llama + **kwargs, + ) + + attn_output = attn_output.reshape(*input_shape, -1).contiguous() + attn_output = self.o_proj(attn_output) + return attn_output, attn_weights + + +@use_kernel_forward_from_hub("RMSNorm") +class Qwen2RMSNorm(nn.Module): + def __init__(self, hidden_size, eps: float = 1e-6) -> None: + """ + Qwen2RMSNorm is equivalent to T5LayerNorm + """ + super().__init__() + self.weight = nn.Parameter(torch.ones(hidden_size)) + self.variance_epsilon = eps + + def forward(self, hidden_states: torch.Tensor) -> torch.Tensor: + input_dtype = hidden_states.dtype + hidden_states = hidden_states.to(torch.float32) + variance = hidden_states.pow(2).mean(-1, keepdim=True) + hidden_states = hidden_states * torch.rsqrt(variance + self.variance_epsilon) + return self.weight * hidden_states.to(input_dtype) + + def extra_repr(self): + return f"{tuple(self.weight.shape)}, eps={self.variance_epsilon}" + + +class Qwen2DecoderLayer(GradientCheckpointingLayer): + def __init__(self, config: Qwen2Config, layer_idx: int): + super().__init__() + self.hidden_size = config.hidden_size + + self.self_attn = Qwen2Attention(config=config, layer_idx=layer_idx) + + self.mlp = Qwen2MLP(config) + self.input_layernorm = Qwen2RMSNorm(config.hidden_size, eps=config.rms_norm_eps) + self.post_attention_layernorm = Qwen2RMSNorm(config.hidden_size, eps=config.rms_norm_eps) + self.attention_type = config.layer_types[layer_idx] + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.Tensor | None = None, + position_ids: torch.LongTensor | None = None, + past_key_values: Cache | None = None, + use_cache: bool | None = False, + cache_position: torch.LongTensor | None = None, + position_embeddings: tuple[torch.Tensor, torch.Tensor] | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> torch.Tensor: + residual = hidden_states + hidden_states = self.input_layernorm(hidden_states) + # Self Attention + hidden_states, _ = self.self_attn( + hidden_states=hidden_states, + attention_mask=attention_mask, + position_ids=position_ids, + past_key_values=past_key_values, + use_cache=use_cache, + cache_position=cache_position, + position_embeddings=position_embeddings, + **kwargs, + ) + hidden_states = residual + hidden_states + + # Fully Connected + residual = hidden_states + hidden_states = self.post_attention_layernorm(hidden_states) + hidden_states = self.mlp(hidden_states) + hidden_states = residual + hidden_states + return hidden_states + + +@auto_docstring +class Qwen2PreTrainedModel(PreTrainedModel): + config: Qwen2Config + base_model_prefix = "model" + supports_gradient_checkpointing = True + _no_split_modules = ["Qwen2DecoderLayer"] + _skip_keys_device_placement = ["past_key_values"] + _supports_flash_attn = True + _supports_sdpa = True + _supports_flex_attn = True + + _can_compile_fullgraph = True + _supports_attention_backend = True + _can_record_outputs = { + "hidden_states": Qwen2DecoderLayer, + "attentions": Qwen2Attention, + } + + +@auto_docstring +class Qwen2Model(Qwen2PreTrainedModel): + def __init__(self, config: Qwen2Config): + super().__init__(config) + self.padding_idx = config.pad_token_id + self.vocab_size = config.vocab_size + + self.embed_tokens = nn.Embedding(config.vocab_size, config.hidden_size, self.padding_idx) + self.layers = nn.ModuleList( + [Qwen2DecoderLayer(config, layer_idx) for layer_idx in range(config.num_hidden_layers)] + ) + self.norm = Qwen2RMSNorm(config.hidden_size, eps=config.rms_norm_eps) + self.rotary_emb = Qwen2RotaryEmbedding(config=config) + self.gradient_checkpointing = False + self.has_sliding_layers = "sliding_attention" in self.config.layer_types + + # Initialize weights and apply final processing + self.post_init() + + @merge_with_config_defaults + @capture_outputs + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.Tensor | None = None, + position_ids: torch.LongTensor | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.FloatTensor | None = None, + use_cache: bool | None = None, + cache_position: torch.LongTensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> BaseModelOutputWithPast: + if (input_ids is None) ^ (inputs_embeds is not None): + raise ValueError("You must specify exactly one of input_ids or inputs_embeds") + + if inputs_embeds is None: + inputs_embeds = self.embed_tokens(input_ids) + + if use_cache and past_key_values is None: + past_key_values = DynamicCache(config=self.config) + + if cache_position is None: + past_seen_tokens = past_key_values.get_seq_length() if past_key_values is not None else 0 + cache_position = torch.arange( + past_seen_tokens, past_seen_tokens + inputs_embeds.shape[1], device=inputs_embeds.device + ) + + if position_ids is None: + position_ids = cache_position.unsqueeze(0) + + # It may already have been prepared by e.g. `generate` + if not isinstance(causal_mask_mapping := attention_mask, dict): + # Prepare mask arguments + mask_kwargs = { + "config": self.config, + "inputs_embeds": inputs_embeds, + "attention_mask": attention_mask, + "cache_position": cache_position, + "past_key_values": past_key_values, + "position_ids": position_ids, + } + # Create the masks + causal_mask_mapping = { + "full_attention": create_causal_mask(**mask_kwargs), + } + # The sliding window alternating layers are not always activated depending on the config + if self.has_sliding_layers: + causal_mask_mapping["sliding_attention"] = create_sliding_window_causal_mask(**mask_kwargs) + + hidden_states = inputs_embeds + position_embeddings = self.rotary_emb(hidden_states, position_ids) + + for decoder_layer in self.layers[: self.config.num_hidden_layers]: + hidden_states = decoder_layer( + hidden_states, + attention_mask=causal_mask_mapping[decoder_layer.attention_type], + position_embeddings=position_embeddings, + position_ids=position_ids, + past_key_values=past_key_values, + use_cache=use_cache, + cache_position=cache_position, + **kwargs, + ) + + hidden_states = self.norm(hidden_states) + return BaseModelOutputWithPast( + last_hidden_state=hidden_states, + past_key_values=past_key_values if use_cache else None, + ) + + +@auto_docstring +class Qwen2ForCausalLM(Qwen2PreTrainedModel, GenerationMixin): + _tied_weights_keys = {"lm_head.weight": "model.embed_tokens.weight"} + _tp_plan = {"lm_head": "colwise_gather_output"} + _pp_plan = {"lm_head": (["hidden_states"], ["logits"])} + + def __init__(self, config): + super().__init__(config) + self.model = Qwen2Model(config) + self.vocab_size = config.vocab_size + self.lm_head = nn.Linear(config.hidden_size, config.vocab_size, bias=False) + + # Initialize weights and apply final processing + self.post_init() + + @can_return_tuple + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.Tensor | None = None, + position_ids: torch.LongTensor | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.FloatTensor | None = None, + labels: torch.LongTensor | None = None, + use_cache: bool | None = None, + cache_position: torch.LongTensor | None = None, + logits_to_keep: int | torch.Tensor = 0, + **kwargs: Unpack[TransformersKwargs], + ) -> CausalLMOutputWithPast: + r""" + Example: + + ```python + >>> from transformers import AutoTokenizer, Qwen2ForCausalLM + + >>> model = Qwen2ForCausalLM.from_pretrained("meta-qwen2/Qwen2-2-7b-hf") + >>> tokenizer = AutoTokenizer.from_pretrained("meta-qwen2/Qwen2-2-7b-hf") + + >>> prompt = "Hey, are you conscious? Can you talk to me?" + >>> inputs = tokenizer(prompt, return_tensors="pt") + + >>> # Generate + >>> generate_ids = model.generate(inputs.input_ids, max_length=30) + >>> tokenizer.batch_decode(generate_ids, skip_special_tokens=True, clean_up_tokenization_spaces=False)[0] + "Hey, are you conscious? Can you talk to me?\nI'm not conscious, but I can talk to you." + ```""" + outputs: BaseModelOutputWithPast = self.model( + input_ids=input_ids, + attention_mask=attention_mask, + position_ids=position_ids, + past_key_values=past_key_values, + inputs_embeds=inputs_embeds, + use_cache=use_cache, + cache_position=cache_position, + **kwargs, + ) + + hidden_states = outputs.last_hidden_state + # Only compute necessary logits, and do not upcast them to float if we are not computing the loss + slice_indices = slice(-logits_to_keep, None) if isinstance(logits_to_keep, int) else logits_to_keep + logits = self.lm_head(hidden_states[:, slice_indices, :]) + + loss = None + if labels is not None: + loss = self.loss_function(logits=logits, labels=labels, vocab_size=self.config.vocab_size, **kwargs) + + return CausalLMOutputWithPast( + loss=loss, + logits=logits, + past_key_values=outputs.past_key_values, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + ) + + +class Qwen2ForSequenceClassification(GenericForSequenceClassification, Qwen2PreTrainedModel): + pass + + +class Qwen2ForTokenClassification(GenericForTokenClassification, Qwen2PreTrainedModel): + pass + + +class Qwen2ForQuestionAnswering(GenericForQuestionAnswering, Qwen2PreTrainedModel): + base_model_prefix = "transformer" # For BC, where `transformer` was used instead of `model` + + +__all__ = [ + "Qwen2PreTrainedModel", + "Qwen2Model", + "Qwen2ForCausalLM", + "Qwen2RMSNorm", + "Qwen2ForSequenceClassification", + "Qwen2ForTokenClassification", + "Qwen2ForQuestionAnswering", +] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/qwen2/modular_qwen2.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/qwen2/modular_qwen2.py new file mode 100644 index 0000000000000000000000000000000000000000..841f901799d7eb0e3dbada651499c91b330fbde7 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/qwen2/modular_qwen2.py @@ -0,0 +1,216 @@ +from collections.abc import Callable + +import torch +from torch import nn + +from ...cache_utils import Cache, DynamicCache +from ...masking_utils import create_causal_mask, create_sliding_window_causal_mask +from ...modeling_flash_attention_utils import FlashAttentionKwargs +from ...modeling_outputs import ( + BaseModelOutputWithPast, +) +from ...modeling_utils import ALL_ATTENTION_FUNCTIONS +from ...processing_utils import Unpack +from ...utils import TransformersKwargs, auto_docstring, logging +from ...utils.generic import merge_with_config_defaults +from ...utils.output_capturing import capture_outputs +from ..gemma2.modeling_gemma2 import Gemma2RotaryEmbedding +from ..llama.modeling_llama import ( + LlamaAttention, + LlamaDecoderLayer, + LlamaForCausalLM, + LlamaForQuestionAnswering, + LlamaForSequenceClassification, + LlamaForTokenClassification, + LlamaMLP, + LlamaPreTrainedModel, + apply_rotary_pos_emb, + eager_attention_forward, +) +from ..mistral.modeling_mistral import MistralModel +from .configuration_qwen2 import Qwen2Config + + +logger = logging.get_logger(__name__) + + +class Qwen2MLP(LlamaMLP): + def __init__(self, config): + super().__init__(config) + self.gate_proj = nn.Linear(self.hidden_size, self.intermediate_size, bias=False) + self.up_proj = nn.Linear(self.hidden_size, self.intermediate_size, bias=False) + self.down_proj = nn.Linear(self.intermediate_size, self.hidden_size, bias=False) + + +class Qwen2RotaryEmbedding(Gemma2RotaryEmbedding): + pass + + +class Qwen2Attention(LlamaAttention): + def __init__(self, config: Qwen2Config, layer_idx: int): + self.layer_type = config.layer_types[layer_idx] if hasattr(config, "layer_types") else None + super().__init__(config, layer_idx) + self.q_proj = nn.Linear(config.hidden_size, config.num_attention_heads * self.head_dim, bias=True) + self.k_proj = nn.Linear(config.hidden_size, config.num_key_value_heads * self.head_dim, bias=True) + self.v_proj = nn.Linear(config.hidden_size, config.num_key_value_heads * self.head_dim, bias=True) + self.o_proj = nn.Linear(config.num_attention_heads * self.head_dim, config.hidden_size, bias=False) + self.sliding_window = config.sliding_window if self.layer_type == "sliding_attention" else None + + def forward( + self, + hidden_states: torch.Tensor, + position_embeddings: tuple[torch.Tensor, torch.Tensor], + attention_mask: torch.Tensor | None, + past_key_values: Cache | None = None, + cache_position: torch.LongTensor | None = None, + **kwargs: Unpack[FlashAttentionKwargs], + ) -> tuple[torch.Tensor, torch.Tensor | None]: + input_shape = hidden_states.shape[:-1] + hidden_shape = (*input_shape, -1, self.head_dim) + + query_states = self.q_proj(hidden_states).view(hidden_shape).transpose(1, 2) + key_states = self.k_proj(hidden_states).view(hidden_shape).transpose(1, 2) + value_states = self.v_proj(hidden_states).view(hidden_shape).transpose(1, 2) + + cos, sin = position_embeddings + query_states, key_states = apply_rotary_pos_emb(query_states, key_states, cos, sin) + + if past_key_values is not None: + # sin and cos are specific to RoPE models; cache_position needed for the static cache + cache_kwargs = {"sin": sin, "cos": cos, "cache_position": cache_position} + key_states, value_states = past_key_values.update(key_states, value_states, self.layer_idx, cache_kwargs) + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, eager_attention_forward + ) + + attn_output, attn_weights = attention_interface( + self, + query_states, + key_states, + value_states, + attention_mask, + dropout=0.0 if not self.training else self.attention_dropout, + scaling=self.scaling, + sliding_window=self.sliding_window, # main diff with Llama + **kwargs, + ) + + attn_output = attn_output.reshape(*input_shape, -1).contiguous() + attn_output = self.o_proj(attn_output) + return attn_output, attn_weights + + +class Qwen2DecoderLayer(LlamaDecoderLayer): + def __init__(self, config: Qwen2Config, layer_idx: int): + super().__init__(config=config, layer_idx=layer_idx) + self.attention_type = config.layer_types[layer_idx] + + +class Qwen2PreTrainedModel(LlamaPreTrainedModel): + pass + + +class Qwen2Model(MistralModel): + def __init__(self, config: Qwen2Config): + super().__init__(config) + self.has_sliding_layers = "sliding_attention" in self.config.layer_types + + @merge_with_config_defaults + @capture_outputs + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.Tensor | None = None, + position_ids: torch.LongTensor | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.FloatTensor | None = None, + use_cache: bool | None = None, + cache_position: torch.LongTensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> BaseModelOutputWithPast: + if (input_ids is None) ^ (inputs_embeds is not None): + raise ValueError("You must specify exactly one of input_ids or inputs_embeds") + + if inputs_embeds is None: + inputs_embeds = self.embed_tokens(input_ids) + + if use_cache and past_key_values is None: + past_key_values = DynamicCache(config=self.config) + + if cache_position is None: + past_seen_tokens = past_key_values.get_seq_length() if past_key_values is not None else 0 + cache_position = torch.arange( + past_seen_tokens, past_seen_tokens + inputs_embeds.shape[1], device=inputs_embeds.device + ) + + if position_ids is None: + position_ids = cache_position.unsqueeze(0) + + # It may already have been prepared by e.g. `generate` + if not isinstance(causal_mask_mapping := attention_mask, dict): + # Prepare mask arguments + mask_kwargs = { + "config": self.config, + "inputs_embeds": inputs_embeds, + "attention_mask": attention_mask, + "cache_position": cache_position, + "past_key_values": past_key_values, + "position_ids": position_ids, + } + # Create the masks + causal_mask_mapping = { + "full_attention": create_causal_mask(**mask_kwargs), + } + # The sliding window alternating layers are not always activated depending on the config + if self.has_sliding_layers: + causal_mask_mapping["sliding_attention"] = create_sliding_window_causal_mask(**mask_kwargs) + + hidden_states = inputs_embeds + position_embeddings = self.rotary_emb(hidden_states, position_ids) + + for decoder_layer in self.layers[: self.config.num_hidden_layers]: + hidden_states = decoder_layer( + hidden_states, + attention_mask=causal_mask_mapping[decoder_layer.attention_type], + position_embeddings=position_embeddings, + position_ids=position_ids, + past_key_values=past_key_values, + use_cache=use_cache, + cache_position=cache_position, + **kwargs, + ) + + hidden_states = self.norm(hidden_states) + return BaseModelOutputWithPast( + last_hidden_state=hidden_states, + past_key_values=past_key_values if use_cache else None, + ) + + +class Qwen2ForCausalLM(LlamaForCausalLM): + pass + + +class Qwen2ForSequenceClassification(LlamaForSequenceClassification): + pass + + +class Qwen2ForTokenClassification(LlamaForTokenClassification): + pass + + +class Qwen2ForQuestionAnswering(LlamaForQuestionAnswering): + pass + + +__all__ = [ + "Qwen2PreTrainedModel", + "Qwen2Model", + "Qwen2ForCausalLM", + "Qwen2RMSNorm", # noqa: F822 + "Qwen2ForSequenceClassification", + "Qwen2ForTokenClassification", + "Qwen2ForQuestionAnswering", +] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/qwen2/tokenization_qwen2.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/qwen2/tokenization_qwen2.py new file mode 100644 index 0000000000000000000000000000000000000000..dc0646beb1a4af285c69b7474bc578e172b53338 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/qwen2/tokenization_qwen2.py @@ -0,0 +1,101 @@ +# Copyright 2024 The Qwen team, Alibaba Group and The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""Tokenization classes for Qwen2.""" + +from tokenizers import AddedToken, Regex, Tokenizer, decoders, normalizers, pre_tokenizers +from tokenizers.models import BPE + +from ...tokenization_utils_tokenizers import TokenizersBackend +from ...utils import logging + + +logger = logging.get_logger(__name__) + +VOCAB_FILES_NAMES = { + "vocab_file": "vocab.json", + "merges_file": "merges.txt", + "tokenizer_file": "tokenizer.json", +} + +MAX_MODEL_INPUT_SIZES = {"qwen/qwen-tokenizer": 32768} + +PRETOKENIZE_REGEX = r"""(?i:'s|'t|'re|'ve|'m|'ll|'d)|[^\r\n\p{L}\p{N}]?\p{L}+|\p{N}| ?[^\s\p{L}\p{N}]+[\r\n]*|\s*[\r\n]+|\s+(?!\S)|\s+""" + + +class Qwen2Tokenizer(TokenizersBackend): + vocab_files_names = VOCAB_FILES_NAMES + model_input_names = ["input_ids", "attention_mask"] + model = BPE + + def __init__( + self, + vocab: str | dict[str, int] | None = None, + merges: str | list[str] | None = None, + unk_token: str = "<|endoftext|>", + bos_token=None, + eos_token: str = "<|endoftext|>", + pad_token: str = "<|endoftext|>", + add_prefix_space=None, + **kwargs, + ): + self.add_prefix_space = add_prefix_space if add_prefix_space is not None else False + self._vocab = ( + vocab + if vocab is not None + else { + "<|endoftext|>": 0, + } + ) + self._merges = merges or [] + self._tokenizer = Tokenizer( + BPE( + vocab=self._vocab, + merges=self._merges, + dropout=None, + unk_token=None, + continuing_subword_prefix="", + end_of_word_suffix="", + fuse_unk=False, + byte_fallback=False, + ) + ) + self._tokenizer.decoder = decoders.ByteLevel() + self._tokenizer.normalizer = normalizers.NFC() + self._tokenizer.pre_tokenizer = pre_tokenizers.Sequence( + [ + pre_tokenizers.Split( + Regex(PRETOKENIZE_REGEX), + behavior="isolated", + invert=False, + ), + pre_tokenizers.ByteLevel( + add_prefix_space=self.add_prefix_space, + use_regex=False, + ), + ] + ) + + super().__init__( + unk_token=unk_token, + bos_token=bos_token, + eos_token=eos_token, + pad_token=pad_token, + add_prefix_space=add_prefix_space, + **kwargs, + ) + + self.add_tokens([AddedToken(token, special=True) for token in self.all_special_tokens]) + + +__all__ = ["Qwen2Tokenizer"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/qwen2_5_omni/__init__.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/qwen2_5_omni/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..0d7ddae0da7e1b2c16b95e94e6678f9511cb716f --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/qwen2_5_omni/__init__.py @@ -0,0 +1,28 @@ +# Copyright 2025 The Qwen Team and The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from typing import TYPE_CHECKING + +from ...utils import _LazyModule +from ...utils.import_utils import define_import_structure + + +if TYPE_CHECKING: + from .configuration_qwen2_5_omni import * + from .modeling_qwen2_5_omni import * + from .processing_qwen2_5_omni import * +else: + import sys + + _file = globals()["__file__"] + sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__) diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/qwen2_5_omni/configuration_qwen2_5_omni.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/qwen2_5_omni/configuration_qwen2_5_omni.py new file mode 100644 index 0000000000000000000000000000000000000000..3d2254e2acf7faa371e610e673faea64c3369da5 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/qwen2_5_omni/configuration_qwen2_5_omni.py @@ -0,0 +1,1031 @@ +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# This file was automatically generated from src/transformers/models/qwen2_5_omni/modular_qwen2_5_omni.py. +# Do NOT edit this file manually as any edits will be overwritten by the generation of +# the file from the modular. If any change should be done, please apply the change to the +# modular_qwen2_5_omni.py file directly. One of our CI enforces this. +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# Copyright 2025 The Qwen team, Alibaba Group and the HuggingFace Inc. team. All rights reserved. +# +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from ...configuration_utils import PreTrainedConfig, layer_type_validation +from ...modeling_rope_utils import RopeParameters +from ...utils import logging + + +logger = logging.get_logger(__name__) + + +class Qwen2_5OmniVisionEncoderConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`Qwen2_5OmniThinkerVision`]. It is used to instantiate a + Qwen2.5-VL vision encoder according to the specified arguments, defining the model architecture. Instantiating a + configuration with the defaults will yield a similar configuration to that of the audio encoder of the Qwen2.5-VL + architecture. + + e.g. [Qwen/Qwen2.5-Omni-7B](https://huggingface.co/Qwen/Qwen2.5-Omni-7B) + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + depth (`int`, *optional*, defaults to 32): + Number of layers (depth) in the model. + hidden_size (`int`, *optional*, defaults to 3584): + The size of the hidden layers. + hidden_act (`str`, *optional*, defaults to `"quick_gelu"`): + The non-linear activation function used in the model. Supported options include `"quick_gelu"` and others as applicable. + mlp_ratio (`float`, *optional*, defaults to 4): + The ratio used to determine the size of the MLP (Multi-Layer Perceptron) hidden layer. + num_heads (`int`, *optional*, defaults to 16): + Number of attention heads for each attention layer. + in_channels (`int`, *optional*, defaults to 3): + Number of input channels. + patch_size (`int`, *optional*, defaults to 14): + The size of the patches extracted from the input. + spatial_merge_size (`int`, *optional*, defaults to 2): + The size used for merging spatial dimensions. + temporal_patch_size (`int`, *optional*, defaults to 2): + The size used for patches along the temporal dimension. + + Example: + + ```python + >>> from transformers import Qwen2_5OmniVisionEncoderConfig, Qwen2_5OmniVisionEncoder + + >>> # Initializing a Qwen2_5OmniVisionEncoderConfig + >>> configuration = Qwen2_5OmniVisionEncoderConfig() + + >>> # Initializing a Qwen2_5OmniVisionEncoder (with random weights) + >>> model = Qwen2_5OmniVisionEncoder(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "qwen2_5_omni_vision_encoder" + base_config_key = "vision_config" + + def __init__( + self, + depth=32, + hidden_size=3584, + hidden_act="silu", + intermediate_size=3420, + num_heads=16, + in_channels=3, + patch_size=14, + spatial_merge_size=2, + temporal_patch_size=2, + window_size=112, + out_hidden_size=3584, + fullatt_block_indexes=[7, 15, 23, 31], + initializer_range=0.02, + **kwargs, + ): + super().__init__(**kwargs) + + self.depth = depth + self.hidden_size = hidden_size + self.hidden_act = hidden_act + self.intermediate_size = intermediate_size + self.num_heads = num_heads + self.in_channels = in_channels + self.patch_size = patch_size + self.spatial_merge_size = spatial_merge_size + self.temporal_patch_size = temporal_patch_size + self.window_size = window_size + self.fullatt_block_indexes = fullatt_block_indexes + self.out_hidden_size = out_hidden_size + self.initializer_range = initializer_range + + +class Qwen2_5OmniAudioEncoderConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`Qwen2_5OmniAudioEncoder`]. It is used to instantiate a + Qwen2.5-Omni-Thinker audio encoder according to the specified arguments, defining the model architecture. Instantiating a + configuration with the defaults will yield a similar configuration to that of the audio encoder of the Qwen2-Audio + architecture. + + e.g. [Qwen/Qwen2.5-Omni-7B](https://huggingface.co/Qwen/Qwen2.5-Omni-7B) + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + num_mel_bins (`int`, *optional*, defaults to 128): + Number of mel features used per input features. Should correspond to the value used in the + `Qwen2_5OmniProcessor` class. + encoder_layers (`int`, *optional*, defaults to 32): + Number of encoder layers. + encoder_attention_heads (`int`, *optional*, defaults to 20): + Number of attention heads for each attention layer in the Transformer encoder. + encoder_ffn_dim (`int`, *optional*, defaults to 5120): + Dimensionality of the "intermediate" (often named feed-forward) layer in encoder. + d_model (`int`, *optional*, defaults to 1280): + Dimensionality of the layers. + dropout (`float`, *optional*, defaults to 0.0): + The dropout probability for all fully connected layers in the embeddings, encoder, and pooler. + attention_dropout (`float`, *optional*, defaults to 0.0): + The dropout ratio for the attention probabilities. + activation_function (`str`, *optional*, defaults to `"gelu"`): + The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`, + `"relu"`, `"silu"` and `"gelu_new"` are supported. + activation_dropout (`float`, *optional*, defaults to 0.0): + The dropout ratio for activations inside the fully connected layer. + scale_embedding (`bool`, *optional*, defaults to `False`): + Scale embeddings by diving by sqrt(d_model). + initializer_range (`float`, *optional*, defaults to 0.02): + The standard deviation of the truncated_normal_initializer for initializing all weight matrices. + max_source_positions (`int`, *optional*, defaults to 1500): + The maximum sequence length of log-mel filter-bank features that this model might ever be used with. + n_window (`int`, *optional*, defaults to 100): + The chunk for conv and flash attn in AudioEncoder. + output_dim (`int`, *optional*, defaults to 3584): + The output dimension of AudioEncoder. + + Example: + + ```python + >>> from transformers import Qwen2_5OmniAudioEncoderConfig, Qwen2_5OmniAudioEncoder + + >>> # Initializing a Qwen2_5OmniAudioEncoderConfig + >>> configuration = Qwen2_5OmniAudioEncoderConfig() + + >>> # Initializing a Qwen2_5OmniAudioEncoder (with random weights) + >>> model = Qwen2_5OmniAudioEncoder(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "qwen2_5_omni_audio_encoder" + + def __init__( + self, + num_mel_bins=128, + encoder_layers=32, + encoder_attention_heads=20, + encoder_ffn_dim=5120, + d_model=1280, + dropout=0, + attention_dropout=0, + activation_function="gelu", + activation_dropout=0, + scale_embedding=False, + initializer_range=0.02, + max_source_positions=1500, + n_window=100, + output_dim=3584, + **kwargs, + ): + super().__init__(**kwargs) + + self.num_mel_bins = num_mel_bins + self.d_model = d_model + self.encoder_layers = encoder_layers + self.encoder_attention_heads = encoder_attention_heads + self.encoder_ffn_dim = encoder_ffn_dim + self.dropout = dropout + self.attention_dropout = attention_dropout + self.activation_function = activation_function + self.activation_dropout = activation_dropout + self.num_hidden_layers = encoder_layers + self.initializer_range = initializer_range + self.scale_embedding = scale_embedding # scale factor will be sqrt(d_model) if True + self.max_source_positions = max_source_positions + self.n_window = n_window + self.output_dim = output_dim + + +class Qwen2_5OmniTextConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`Qwen2_5OmniThinkerForConditionalGeneration`]. It is used to instantiate an + Qwen2.5-Omni-Thinker model according to the specified arguments, defining the model architecture. Instantiating a configuration + with the defaults will yield a similar configuration to that of the Qwen2.5-Omni-Thinker. + + e.g. [Qwen/Qwen2.5-Omni-7B](https://huggingface.co/Qwen/Qwen2.5-Omni-7B) + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + vocab_size (`int`, *optional*, defaults to 152064): + Vocabulary size of the QwenOmni model. Defines the number of different tokens that can be represented by the + `inputs_ids` passed when calling [`Qwen2VLModel`] + hidden_size (`int`, *optional*, defaults to 3584): + Dimension of the hidden representations. + intermediate_size (`int`, *optional*, defaults to 18944): + Dimension of the MLP representations. + num_hidden_layers (`int`, *optional*, defaults to 28): + Number of hidden layers in the Transformer encoder. + num_attention_heads (`int`, *optional*, defaults to 28): + Number of attention heads for each attention layer in the Transformer encoder. + num_key_value_heads (`int`, *optional*, defaults to 4): + This is the number of key_value heads that should be used to implement Grouped Query Attention. If + `num_key_value_heads=num_attention_heads`, the model will use Multi Head Attention (MHA), if + `num_key_value_heads=1` the model will use Multi Query Attention (MQA) otherwise GQA is used. When + converting a multi-head checkpoint to a GQA checkpoint, each group key and value head should be constructed + by meanpooling all the original heads within that group. For more details, check out [this + paper](https://huggingface.co/papers/2305.13245). If it is not specified, will default to `32`. + hidden_act (`str` or `function`, *optional*, defaults to `"silu"`): + The non-linear activation function (function or string) in the decoder. + max_position_embeddings (`int`, *optional*, defaults to 32768): + The maximum sequence length that this model might ever be used with. + rms_norm_eps (`float`, *optional*, defaults to 1e-06): + The epsilon used by the rms normalization layers. + use_cache (`bool`, *optional*, defaults to `True`): + Whether or not the model should return the last key/values attentions (not used by all models). Only + relevant if `config.is_decoder=True`. + use_sliding_window (`bool`, *optional*, defaults to `False`): + Whether to use sliding window attention. + sliding_window (`int`, *optional*, defaults to 32768): + Sliding window attention (SWA) window size. If not specified, will default to `4096`. + max_window_layers (`int`, *optional*, defaults to 28): + The number of layers using full attention. The first `max_window_layers` layers will use full attention, while any + additional layer afterwards will use SWA (Sliding Window Attention). + layer_types (`list`, *optional*): + Attention pattern for each layer. + attention_dropout (`float`, *optional*, defaults to 0.0): + The dropout ratio for the attention probabilities. + rope_parameters (`RopeParameters`, *optional*): + Dictionary containing the configuration parameters for the RoPE embeddings. The dictionary should contain + a value for `rope_theta` and optionally parameters used for scaling in case you want to use RoPE + with longer `max_position_embeddings`. + initializer_range (`float`, *optional*, defaults to 0.02): + The standard deviation of the truncated_normal_initializer for initializing all weight matrices. + tie_word_embeddings (`bool`, *optional*, defaults to `True`): + Whether to tie weight embeddings + + Example: + + ```python + >>> from transformers import Qwen2_5OmniThinkerForConditionalGeneration, Qwen2_5OmniThinkerConfig, Qwen2_5OmniAudioEncoderConfig, Qwen2_5OmniVisionEncoderConfig + + >>> # Initializing a Qwen2_5OmniAudioEncoder config + >>> audio_config = Qwen2_5OmniAudioEncoderConfig() + + >>> # Initializing a Qwen2_5OmniVisionEncoder config + >>> vision_config = Qwen2_5OmniVisionEncoderConfig() + + >>> # Initializing a Qwen2.5OmniThinker configuration + >>> configuration = Qwen2_5OmniThinkerConfig(audio_config, vision_config) + + >>> # Initializing a model from the Qwen-Omni style configuration + >>> model = Qwen2_5OmniThinkerForConditionalGeneration(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "qwen2_5_omni_text" + keys_to_ignore_at_inference = ["past_key_values"] + default_theta = 1000000.0 + + # Default tensor parallel plan for base model `Qwen25OmniText` + base_model_tp_plan = { + "layers.*.self_attn.q_proj": "colwise", + "layers.*.self_attn.k_proj": "colwise", + "layers.*.self_attn.v_proj": "colwise", + "layers.*.self_attn.o_proj": "rowwise", + "layers.*.mlp.gate_proj": "colwise", + "layers.*.mlp.up_proj": "colwise", + "layers.*.mlp.down_proj": "rowwise", + } + base_model_pp_plan = { + "embed_tokens": (["input_ids"], ["inputs_embeds"]), + "layers": (["hidden_states", "attention_mask"], ["hidden_states"]), + "norm": (["hidden_states"], ["hidden_states"]), + } + + def __init__( + self, + vocab_size: int | None = 152064, + hidden_size: int | None = 3584, + intermediate_size: int | None = 18944, + num_hidden_layers: int | None = 28, + num_attention_heads: int | None = 28, + num_key_value_heads: int | None = 4, + hidden_act: str | None = "silu", + max_position_embeddings: int | None = 32768, + initializer_range: float | None = 0.02, + rms_norm_eps: int | None = 1e-6, + use_cache: bool | None = True, + rope_parameters: RopeParameters | dict[str, RopeParameters] | None = None, + use_sliding_window: bool | None = False, + sliding_window: int | None = 32768, + max_window_layers: int | None = 28, + layer_types: list[str] | None = None, + attention_dropout: float | None = 0.0, + pad_token_id: int | None = None, + bos_token_id: int | None = None, + eos_token_id: int | None = None, + tie_word_embeddings: bool | None = True, + **kwargs, + ): + self.vocab_size = vocab_size + self.max_position_embeddings = max_position_embeddings + self.hidden_size = hidden_size + self.intermediate_size = intermediate_size + self.num_hidden_layers = num_hidden_layers + self.num_attention_heads = num_attention_heads + self.use_sliding_window = use_sliding_window + self.sliding_window = sliding_window if self.use_sliding_window else None + self.max_window_layers = max_window_layers + self.pad_token_id = pad_token_id + self.bos_token_id = bos_token_id + self.eos_token_id = eos_token_id + self.tie_word_embeddings = tie_word_embeddings + + # for backward compatibility + if num_key_value_heads is None: + num_key_value_heads = num_attention_heads + + self.num_key_value_heads = num_key_value_heads + self.hidden_act = hidden_act + self.initializer_range = initializer_range + self.rms_norm_eps = rms_norm_eps + self.use_cache = use_cache + self.attention_dropout = attention_dropout + + self.layer_types = layer_types + if self.layer_types is None: + self.layer_types = [ + "sliding_attention" + if self.sliding_window is not None and i >= self.max_window_layers + else "full_attention" + for i in range(self.num_hidden_layers) + ] + layer_type_validation(self.layer_types, self.num_hidden_layers) + + self.rope_parameters = rope_parameters + super().__init__( + ignore_keys_at_rope_validation={"mrope_section"}, + **kwargs, + ) + + +class Qwen2_5OmniThinkerConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`Qwen2_5OmniThinkerForConditionalGeneration`]. It is used to instantiate an + Qwen2.5-Omni-Thinker model according to the specified arguments, defining the model architecture. Instantiating a configuration + with the defaults will yield a similar configuration to that of the Qwen2.5-Omni-Thinker. + + e.g. [Qwen/Qwen2.5-Omni-7B](https://huggingface.co/Qwen/Qwen2.5-Omni-7B) + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + audio_config (`dict`, *optional*): + The config dictionary of the audio backbone. + vision_config (`dict`, *optional*): + The config dictionary of the vision backbone. + text_config (`dict`, *optional*): + The config dictionary of the text backbone. + audio_token_index (`int`, *optional*, defaults to 151646): + The audio token index to encode the audio prompt. + image_token_index (`int`, *optional*, defaults to 151655): + The image token index to encode the image prompt. + video_token_index (`int`, *optional*, defaults to 151656): + The video token index to encode the video prompt. + position_id_per_seconds (`int`, *optional*, defaults to 25): + The increment of position id per second. + seconds_per_chunk (`int`, *optional*, defaults to 2): + The duration in seconds of the chunk of audio and video data. + audio_start_token_id (`int`, *optional*, defaults to 151647): + The audio start token index to encode the audio prompt. + audio_end_token_id (`int`, *optional*, defaults to 151648): + The audio end token index to encode the audio prompt. + user_token_id (`int, *optional*, defaults to 872): + The user token index to encode the user token. + initializer_range (`float`, *optional*, defaults to 0.02): + The standard deviation of the truncated_normal_initializer for initializing all weight matrices. + tie_word_embeddings (`bool`, *optional*, defaults to `False`): + Whether the model's input and output word embeddings should be tied. + + Example: + + ```python + >>> from transformers import Qwen2_5OmniThinkerForConditionalGeneration, Qwen2_5OmniThinkerConfig, Qwen2_5OmniAudioEncoderConfig, Qwen2_5OmniVisionEncoderConfig + + >>> # Initializing a Qwen2_5OmniAudioEncoder config + >>> audio_config = Qwen2_5OmniAudioEncoderConfig() + + >>> # Initializing a Qwen2_5OmniVisionEncoder config + >>> vision_config = Qwen2_5OmniVisionEncoderConfig() + + >>> # Initializing a Qwen2_5OmniTextConfig config + >>> text_config = Qwen2_5OmniTextConfig() + + >>> # Initializing a Qwen2.5OmniThinker configuration + >>> configuration = Qwen2_5OmniThinkerConfig(audio_config, vision_config, text_config) + + >>> # Initializing a model from the Qwen-Omni style configuration + >>> model = Qwen2_5OmniThinkerForConditionalGeneration(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "qwen2_5_omni_thinker" + attribute_map = { + "image_token_id": "image_token_index", + "video_token_id": "video_token_index", + "audio_token_id": "audio_token_index", + } + sub_configs = { + "audio_config": Qwen2_5OmniAudioEncoderConfig, + "vision_config": Qwen2_5OmniVisionEncoderConfig, + "text_config": Qwen2_5OmniTextConfig, + } + + def __init__( + self, + audio_config=None, + vision_config=None, + text_config=None, + audio_token_index=151646, + image_token_index=151655, + video_token_index=151656, + position_id_per_seconds=25, + seconds_per_chunk=2, + audio_start_token_id=151647, + audio_end_token_id=151648, + user_token_id=872, + initializer_range=0.02, + tie_word_embeddings=False, + **kwargs, + ): + self.audio_token_index = audio_token_index + self.image_token_index = image_token_index + self.video_token_index = video_token_index + self.user_token_id = user_token_id + self.position_id_per_seconds = position_id_per_seconds + self.seconds_per_chunk = seconds_per_chunk + self.audio_start_token_id = audio_start_token_id + self.audio_end_token_id = audio_end_token_id + self.initializer_range = initializer_range + self.tie_word_embeddings = tie_word_embeddings + + if isinstance(vision_config, dict): + vision_config = Qwen2_5OmniVisionEncoderConfig(**vision_config) + elif vision_config is None: + vision_config = Qwen2_5OmniVisionEncoderConfig() + self.vision_config = vision_config + + if isinstance(audio_config, dict): + audio_config = Qwen2_5OmniAudioEncoderConfig(**audio_config) + elif audio_config is None: + audio_config = Qwen2_5OmniAudioEncoderConfig() + self.audio_config = audio_config + + if isinstance(text_config, dict): + text_config = Qwen2_5OmniTextConfig(**text_config) + elif text_config is None: + text_config = Qwen2_5OmniTextConfig() + self.text_config = text_config + + super().__init__(**kwargs) + + +class Qwen2_5OmniTalkerConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`Qwen2_5OmniTalkerForConditionalGeneration`]. It is used to instantiate an + Qwen2.5-Omni-Talker model according to the specified arguments, defining the model architecture. Instantiating a configuration + with the defaults will yield a similar configuration to that of the Qwen2.5-Omni-Thinker. + + e.g. [Qwen/Qwen2.5-Omni-7B](https://huggingface.co/Qwen/Qwen2.5-Omni-7B) + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + audio_token_index (`int`, *optional*, defaults to 151646): + The audio token index to encode the audio prompt. + image_token_index (`int`, *optional*, defaults to 151655): + The image token index to encode the image prompt. + video_token_index (`int`, *optional*, defaults to 151656): + The video token index to encode the video prompt. + vocab_size (`int`, *optional*, defaults to 8448): + Vocabulary size of the QwenOmni model. Defines the number of different tokens that can be represented by the + `inputs_ids` passed when calling [`Qwen2VLModel`] + tts_text_start_token_id (`int`, *optional*, defaults to 151860): + The tts text start token index to encode the start of tts text. + tts_text_end_token_id (`int`, *optional*, defaults to 151861): + The tts text end token index to encode the end of tts text. + tts_text_pad_token_id (`int`, *optional*, defaults to 151859): + The tts text pad token index to encode the pad of tts text. + tts_codec_start_token_id (`int`, *optional*, defaults to 8293): + The tts codec start token index to encode the start of tts codec. + tts_codec_end_token_id (`int`, *optional*, defaults to 8294): + The tts codec end token index to encode the end of tts codec. + tts_codec_pad_token_id (`int`, *optional*, defaults to 8292): + The tts codec pad token index to encode the pad of tts codec. + tts_codec_mask_token_id (`int`, *optional*, defaults to 8296): + The tts codec mask token index to encode the mask of tts codec. + vision_start_token_id (`int`, *optional*, defaults to 151652): + The tts vision start token index to encode the start of vision. + vision_end_token_id (`int`, *optional*, defaults to 151653): + The tts vision end token index to encode the end of vision. + embedding_size (`int`, *optional*, defaults to 3584): + Dimension of the embedding representations. + hidden_size (`int`, *optional*, defaults to 3584): + Dimension of the hidden representations. + intermediate_size (`int`, *optional*, defaults to 18944): + Dimension of the MLP representations. + num_hidden_layers (`int`, *optional*, defaults to 28): + Number of hidden layers in the Transformer encoder. + num_attention_heads (`int`, *optional*, defaults to 28): + Number of attention heads for each attention layer in the Transformer encoder. + num_key_value_heads (`int`, *optional*, defaults to 4): + This is the number of key_value heads that should be used to implement Grouped Query Attention. If + `num_key_value_heads=num_attention_heads`, the model will use Multi Head Attention (MHA), if + `num_key_value_heads=1` the model will use Multi Query Attention (MQA) otherwise GQA is used. When + converting a multi-head checkpoint to a GQA checkpoint, each group key and value head should be constructed + by meanpooling all the original heads within that group. For more details, check out [this + paper](https://huggingface.co/papers/2305.13245). If it is not specified, will default to `32`. + hidden_act (`str` or `function`, *optional*, defaults to `"silu"`): + The non-linear activation function (function or string) in the decoder. + max_position_embeddings (`int`, *optional*, defaults to 32768): + The maximum sequence length that this model might ever be used with. + rms_norm_eps (`float`, *optional*, defaults to 1e-06): + The epsilon used by the rms normalization layers. + head_dim (`int`, *optional*, defaults to 128): + The dimension of each attention head. + use_cache (`bool`, *optional*, defaults to `True`): + Whether or not the model should return the last key/values attentions (not used by all models). Only + relevant if `config.is_decoder=True`. + tie_word_embeddings (`bool`, *optional*, defaults to `False`): + Whether the model's input and output word embeddings should be tied. + use_sliding_window (`bool`, *optional*, defaults to `False`): + Whether to use sliding window attention. + sliding_window (`int`, *optional*, defaults to 32768): + Sliding window attention (SWA) window size. If not specified, will default to `4096`. + max_window_layers (`int`, *optional*, defaults to 28): + The number of layers using full attention. The first `max_window_layers` layers will use full attention, while any + additional layer afterwards will use SWA (Sliding Window Attention). + attention_dropout (`float`, *optional*, defaults to 0.0): + The dropout ratio for the attention probabilities. + rope_parameters (`RopeParameters`, *optional*): + Dictionary containing the configuration parameters for the RoPE embeddings. The dictionary should contain + a value for `rope_theta` and optionally parameters used for scaling in case you want to use RoPE + with longer `max_position_embeddings`. + position_id_per_seconds (`int`, *optional*, defaults to 25): + The increment of position id per second. + seconds_per_chunk (`int`, *optional*, defaults to 2): + The duration in seconds of the chunk of audio and video data. + audio_start_token_id (`int`, *optional*, defaults to 151647): + The audio start token index to encode the audio prompt. + audio_end_token_id (`int`, *optional*, defaults to 151648): + The audio end token index to encode the audio prompt. + initializer_range (`float`, *optional*, defaults to 0.02): + The standard deviation of the truncated_normal_initializer for initializing all weight matrices. + spatial_merge_size (`int`, *optional*, defaults to 2): + The size used for merging spatial dimensions. + layer_types (`list`, *optional*): + Attention pattern for each layer. + pad_token_id (`int`, *optional*): + The id of the padding token. + + + Example: + + ```python + >>> from transformers import Qwen2_5OmniTalkerForConditionalGeneration, Qwen2_5OmniThinkerConfig, Qwen2_5OmniAudioEncoderConfig, Qwen2_5OmniVisionEncoderConfig + + >>> # Initializing a Qwen2_5OmniAudioEncoder config + >>> audio_config = Qwen2_5OmniAudioEncoderConfig() + + >>> # Initializing a Qwen2 config + >>> text_config = Qwen2Config() + + >>> # Initializing a Qwen2_5Omni configuration + >>> configuration = Qwen2_5OmniThinkerConfig(audio_config, text_config) + + >>> # Initializing a model from the qwen2-audio style configuration + >>> model = Qwen2_5OmniTalkerForConditionalGeneration(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "qwen2_5_omni_talker" + default_theta = 1000000.0 + attribute_map = { + "image_token_id": "image_token_index", + "video_token_id": "video_token_index", + "audio_token_id": "audio_token_index", + } + + def __init__( + self, + audio_token_index=151646, + image_token_index=151655, + video_token_index=151656, + vocab_size=8448, + tts_text_start_token_id=151860, + tts_text_end_token_id=151861, + tts_text_pad_token_id=151859, + tts_codec_start_token_id=8293, + tts_codec_end_token_id=8294, + tts_codec_pad_token_id=8292, + tts_codec_mask_token_id=8296, + vision_start_token_id=151652, + vision_end_token_id=151653, + embedding_size=3584, + hidden_size=3584, + intermediate_size=18944, + num_hidden_layers=28, + num_attention_heads=28, + num_key_value_heads=4, + hidden_act="silu", + max_position_embeddings=32768, + rms_norm_eps=1e-06, + head_dim=128, + use_cache=True, + tie_word_embeddings=False, + use_sliding_window=False, + sliding_window=32768, + max_window_layers=28, + attention_dropout=0.0, + rope_parameters: RopeParameters | dict[str, RopeParameters] | None = None, + position_id_per_seconds=25, + seconds_per_chunk=2, + audio_start_token_id=151647, + audio_end_token_id=151648, + initializer_range=0.02, + spatial_merge_size=2, + layer_types=None, + pad_token_id: int | None = None, + **kwargs, + ): + self.audio_token_index = audio_token_index + self.image_token_index = image_token_index + self.video_token_index = video_token_index + + self.tts_text_start_token_id = tts_text_start_token_id + self.tts_text_end_token_id = tts_text_end_token_id + self.tts_text_pad_token_id = tts_text_pad_token_id + self.tts_codec_start_token_id = tts_codec_start_token_id + self.tts_codec_end_token_id = tts_codec_end_token_id + self.tts_codec_pad_token_id = tts_codec_pad_token_id + + self.tts_codec_mask_token_id = tts_codec_mask_token_id + + self.vision_start_token_id = vision_start_token_id + self.vision_end_token_id = vision_end_token_id + + self.vocab_size = vocab_size + self.head_dim = head_dim + self.embedding_size = embedding_size + self.max_position_embeddings = max_position_embeddings + self.hidden_size = hidden_size + self.intermediate_size = intermediate_size + self.num_hidden_layers = num_hidden_layers + self.num_attention_heads = num_attention_heads + self.use_sliding_window = use_sliding_window + self.sliding_window = sliding_window if self.use_sliding_window else None + self.max_window_layers = max_window_layers + + # for backward compatibility + if num_key_value_heads is None: + num_key_value_heads = num_attention_heads + + self.num_key_value_heads = num_key_value_heads + self.hidden_act = hidden_act + self.rms_norm_eps = rms_norm_eps + self.use_cache = use_cache + self.attention_dropout = attention_dropout + self.position_id_per_seconds = position_id_per_seconds # zf + self.seconds_per_chunk = seconds_per_chunk # zf + self.audio_start_token_id = audio_start_token_id # zf + self.audio_end_token_id = audio_end_token_id # zf + self.pad_token_id = pad_token_id + + self.initializer_range = initializer_range + self.spatial_merge_size = spatial_merge_size + self.tie_word_embeddings = tie_word_embeddings + + self.layer_types = layer_types + if self.layer_types is None: + self.layer_types = [ + "sliding_attention" + if self.sliding_window is not None and i >= self.max_window_layers + else "full_attention" + for i in range(self.num_hidden_layers) + ] + layer_type_validation(self.layer_types, self.num_hidden_layers) + + self.rope_parameters = rope_parameters + super().__init__(ignore_keys_at_rope_validation={"mrope_section"}, **kwargs) + + +class Qwen2_5OmniDiTConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of the Qwen2_5OmniToken2WavDiT used in the Qwen2.5-Omni-Token2Wav model. + It defines the architecture of the DiT model, which is used for generating mel-spectrograms from tokens. + + Args: + hidden_size (`int`, *optional*, defaults to 1024): + The dimension of the model. + num_hidden_layers (`int`, *optional*, defaults to 22): + The number of transformer blocks in the DiT model. + num_attention_heads (`int`, *optional*, defaults to 16): + The number of attention heads in each transformer block. + ff_mult (`int`, *optional*, defaults to 2): + The multiplier for the feedforward layer in each transformer block. + emb_dim (`int`, *optional*, defaults to 512): + The dimension of the embedding layer. + head_dim (`int`, *optional*, defaults to 64): + The dimension of each attention head. + repeats (`int`, *optional*, defaults to 2): + The number of times the codec embeddings are repeated. + num_embeds (`int`, *optional*, defaults to 8193): + The number of unique embeddings in the codec. + mel_dim (`int`, *optional*, defaults to 80): + The dimension of the mel-spectrogram. + dropout (`float`, *optional*, defaults to 0.1): + The dropout rate for the transformer blocks. + + enc_emb_dim (`int`, *optional*, defaults to 192): + The dimension of the pre-trained speaker embedding. + enc_dim (`int`, *optional*, defaults to 128): + The dimension of the encoder output. + enc_channels (`list[int]`, *optional*, defaults to `[256, 256, 256, 256, 768]`): + A list of output channels for each TDNN/SERes2Net layer in the encoder. + enc_kernel_sizes (`list[int]`, *optional*, defaults to `[5, 3, 3, 3, 1]`): + A list of kernel sizes for each layer in the encoder. + enc_dilations (`list[int]`, *optional*, defaults to `[1, 2, 3, 4, 1]`): + A list of dilations for each layer in the encoder. + enc_attention_channels (`int`, *optional*, defaults to 64): + The number of attention channels in the SqueezeExcitationBlock. + enc_res2net_scale (`int`, *optional*, defaults to 2): + The scale of the Res2Net block in the encoder. + enc_se_channels (`int`, *optional*, defaults to 64): + The number of output channels after squeeze in the SqueezeExcitationBlock. + """ + + model_type = "qwen2_5_omni_dit" + + def __init__( + self, + hidden_size=1024, + num_hidden_layers=22, + num_attention_heads=16, + ff_mult=2, + emb_dim=512, + head_dim=64, + rope_parameters: RopeParameters | dict[str, RopeParameters] | None = None, + max_position_embeddings=32768, + block_size=24, + look_ahead_layers=[10], + look_backward_layers=[0, 20], + repeats=2, + num_embeds=8193, + mel_dim=80, + dropout=0.1, + enc_emb_dim=192, + enc_dim=128, + enc_channels=[256, 256, 256, 256, 768], + enc_kernel_sizes=[5, 3, 3, 3, 1], + enc_dilations=[1, 2, 3, 4, 1], + enc_attention_channels=64, + enc_res2net_scale=2, + enc_se_channels=64, + **kwargs, + ): + self.hidden_size = hidden_size + self.num_hidden_layers = num_hidden_layers + self.num_attention_heads = num_attention_heads + self.ff_mult = ff_mult + self.emb_dim = emb_dim + self.head_dim = head_dim + self.max_position_embeddings = max_position_embeddings + self.block_size = block_size + self.look_ahead_layers = look_ahead_layers + self.look_backward_layers = look_backward_layers + self.repeats = repeats + self.num_embeds = num_embeds + self.mel_dim = mel_dim + self.dropout = dropout + self.enc_emb_dim = enc_emb_dim + self.enc_dim = enc_dim + self.enc_channels = enc_channels + self.enc_kernel_sizes = enc_kernel_sizes + self.enc_dilations = enc_dilations + self.enc_attention_channels = enc_attention_channels + self.enc_res2net_scale = enc_res2net_scale + self.enc_se_channels = enc_se_channels + self.rope_parameters = rope_parameters + + super().__init__(**kwargs) + + +class Qwen2_5OmniBigVGANConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of the Qwen2_5OmniToken2WavBigVGAN module used in the Qwen2.5-Omni-Token2Wav model. + It defines the architecture of the BigVGAN model, which is used for converting mel-spectrograms to waveforms. + + Args: + mel_dim (`int`, *optional*, defaults to 80): + The dimension of the mel-spectrogram. + upsample_initial_channel (`int`, *optional*, defaults to 1536): + The number of channels in the initial upsampling layer. + resblock_kernel_sizes (`list[int]`, *optional*, defaults to `[3, 7, 11]`): + A list of kernel sizes for each residual block. + resblock_dilation_sizes (`list[list[int]]`, *optional*, defaults to `[[1, 3, 5], [1, 3, 5], [1, 3, 5]]`): + A list of dilation sizes for each residual block. + upsample_rates (`list[int]`, *optional*, defaults to `[5, 3, 2, 2, 2, 2]`): + A list of upsampling rates for each upsampling layer. + upsample_kernel_sizes (`list[int]`, *optional*, defaults to `[11, 7, 4, 4, 4, 4]`): + A list of kernel sizes for each upsampling layer. + """ + + model_type = "qwen2_5_omni_bigvgan" + + def __init__( + self, + mel_dim=80, + upsample_initial_channel=1536, + resblock_kernel_sizes=[3, 7, 11], + resblock_dilation_sizes=[[1, 3, 5], [1, 3, 5], [1, 3, 5]], + upsample_rates=[5, 3, 2, 2, 2, 2], + upsample_kernel_sizes=[11, 7, 4, 4, 4, 4], + **kwargs, + ): + self.mel_dim = mel_dim + self.upsample_initial_channel = upsample_initial_channel + self.resblock_kernel_sizes = resblock_kernel_sizes + self.resblock_dilation_sizes = resblock_dilation_sizes + self.upsample_rates = upsample_rates + self.upsample_kernel_sizes = upsample_kernel_sizes + super().__init__(**kwargs) + + +class Qwen2_5OmniToken2WavConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`Qwen2_5OmniToken2WavModel`]. + It is used to instantiate the Qwen2.5-Omni-Token2Wav model which combines a Diffusion Transformer (DiT) for mel-spectrogram generation with a BigVGAN model for waveform synthesis. The configuration contains sub-configurations for both components. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + dit_config ([`DiT_Args`], *optional*): + Configuration class for the Diffusion Transformer (DiT) module responsible for generating mel-spectrograms. + bigvgan_config ([`BigVGAN_Args`], *optional*): + Configuration class for the BigVGAN module responsible for converting mel-spectrograms to waveforms. + Example: + + ```python + >>> from transformers import Qwen2_5OmniToken2WavModel, DiT_Args, BigVGAN_Args + + >>> # Initialize DiT configuration + >>> dit_config = DiT_Args( + ... dim=1024, + ... depth=22, + ... heads=16, + ... ff_mult=2 + ... ) + + >>> # Initialize BigVGAN configuration + >>> bigvgan_config = BigVGAN_Args( + ... mel_dim=80, + ... upsample_rates=[5,3,2,2,2,2] + ... ) + + >>> # Initialize main configuration + >>> config = Qwen2_5OmniToken2WavConfig(dit_config, bigvgan_config) + + >>> # Initialize model with config + >>> model = Qwen2_5OmniToken2Wav(config) + + >>> # Accessing the model configuration + >>> configuration = model.config + ``` + """ + + model_type = "qwen2_5_omni_token2wav" + sub_configs = { + "dit_config": Qwen2_5OmniDiTConfig, + "bigvgan_config": Qwen2_5OmniBigVGANConfig, + } + + def __init__(self, dit_config=None, bigvgan_config=None, **kwargs): + if dit_config is None: + dit_config = {} + if bigvgan_config is None: + bigvgan_config = {} + self.dit_config = Qwen2_5OmniDiTConfig(**dit_config) + self.bigvgan_config = Qwen2_5OmniBigVGANConfig(**bigvgan_config) + super().__init__(**kwargs) + + +class Qwen2_5OmniConfig(PreTrainedConfig): + """ + This is the configuration class to store the configuration of a [`Qwen2_5OmniForConditionalGeneration`]. It is used to instantiate a Qwen2.5Omni + model according to the specified sub-models configurations, defining the model architecture. + + Instantiating a configuration with the defaults will yield a similar configuration to that of the + [Qwen/Qwen2.5-Omni-7B](https://huggingface.co/Qwen/Qwen2.5-Omni-7B) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + thinker_config (`dict`, *optional*): Configuration of the underlying thinker sub-model. + talker_config (`dict`, *optional*): Configuration of the underlying talker sub-model. + token2wav_config (`dict`, *optional*): Configuration of the underlying codec sub-model. + enable_audio_output (`bool`, *optional*, defaults to `True`): Whether enable audio output and load talker and token2wav module. + + Example: + + ```python + >>> from transformers import ( + ... Qwen2_5OmniThinkerConfig, + ... Qwen2_5OmniTalkerConfig, + ... Qwen2_5OmniToken2WavConfig, + ... Qwen2_5OmniForConditionalGeneration, + ... Qwen2_5OmniConfig, + ... ) + + >>> # Initializing sub-modules configurations. + >>> thinker_config = Qwen2_5OmniThinkerConfig() + >>> talker_config = Qwen2_5OmniTalkerConfig() + >>> token2wav_config = Qwen2_5OmniToken2WavConfig() + + + >>> # Initializing a module style configuration + >>> configuration = Qwen2_5OmniConfig( + ... thinker_config, talker_config, token2wav_config + ... ) + + >>> # Initializing a model (with random weights) + >>> model = Qwen2_5OmniForConditionalGeneration(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ``` + """ + + model_type = "qwen2_5_omni" + sub_configs = { + "thinker_config": Qwen2_5OmniThinkerConfig, + "talker_config": Qwen2_5OmniTalkerConfig, + "token2wav_config": Qwen2_5OmniToken2WavConfig, + } + + def __init__( + self, + thinker_config=None, + talker_config=None, + token2wav_config=None, + enable_audio_output: bool = True, + **kwargs, + ): + if thinker_config is None: + thinker_config = {} + logger.info("thinker_config is None. Initializing thinker model with default values") + + if talker_config is None: + talker_config = {} + logger.info("talker_config is None. Initializing talker model with default values") + + if token2wav_config is None: + token2wav_config = {} + logger.info("token2wav_config is None. Initializing token2wav model with default values") + + self.thinker_config = Qwen2_5OmniThinkerConfig(**thinker_config) + self.talker_config = Qwen2_5OmniTalkerConfig(**talker_config) + self.token2wav_config = Qwen2_5OmniToken2WavConfig(**token2wav_config) + self.enable_audio_output = enable_audio_output + + super().__init__(**kwargs) + + def get_text_config(self, *args, **kwargs): + """ + Returns the config that is meant to be used with text IO. On most models, it is the original config instance + itself. On specific composite models, it is under a set of valid names. + + Args: + decoder (`Optional[bool]`, *optional*, defaults to `False`): + If set to `True`, then only search for decoder config names. + """ + # Overridden for deeply nested config like Qwen2-Omni. We don't have any omni model + # except for Qwen yet. This has to be generalized if more deeply nested configs are + # added. NOTE: currently method used only by vLLM + return self.thinker_config.get_text_config(*args, **kwargs) + + +__all__ = ["Qwen2_5OmniConfig", "Qwen2_5OmniThinkerConfig", "Qwen2_5OmniTalkerConfig", "Qwen2_5OmniToken2WavConfig"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/qwen2_5_omni/modeling_qwen2_5_omni.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/qwen2_5_omni/modeling_qwen2_5_omni.py new file mode 100644 index 0000000000000000000000000000000000000000..e484989846373e6725ffa73b54c0b4d3805ce0c5 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/qwen2_5_omni/modeling_qwen2_5_omni.py @@ -0,0 +1,4126 @@ +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# This file was automatically generated from src/transformers/models/qwen2_5_omni/modular_qwen2_5_omni.py. +# Do NOT edit this file manually as any edits will be overwritten by the generation of +# the file from the modular. If any change should be done, please apply the change to the +# modular_qwen2_5_omni.py file directly. One of our CI enforces this. +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# Copyright 2025 The Qwen team, Alibaba Group and the HuggingFace Inc. team. All rights reserved. +# +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import math +from collections.abc import Callable +from dataclasses import dataclass +from typing import Any, Optional + +import numpy as np +import torch +import torch.nn.functional as F +from torch import nn +from torch.nn import Parameter + +from ... import initialization as init +from ...activations import ACT2FN +from ...cache_utils import Cache, DynamicCache +from ...generation import GenerationMixin +from ...integrations import use_kernel_forward_from_hub +from ...masking_utils import create_causal_mask, create_sliding_window_causal_mask +from ...modeling_flash_attention_utils import FlashAttentionKwargs +from ...modeling_layers import GradientCheckpointingLayer +from ...modeling_outputs import BaseModelOutputWithPast, BaseModelOutputWithPooling, ModelOutput +from ...modeling_rope_utils import ROPE_INIT_FUNCTIONS, dynamic_rope_update +from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel +from ...processing_utils import Unpack +from ...utils import ( + TransformersKwargs, + auto_docstring, + can_return_tuple, + check_torch_load_is_safe, + logging, + torch_compilable_check, +) +from ...utils.deprecation import deprecate_kwarg +from ...utils.generic import is_flash_attention_requested, maybe_autocast, merge_with_config_defaults +from ...utils.hub import cached_file +from ...utils.output_capturing import capture_outputs +from .configuration_qwen2_5_omni import ( + Qwen2_5OmniAudioEncoderConfig, + Qwen2_5OmniBigVGANConfig, + Qwen2_5OmniConfig, + Qwen2_5OmniDiTConfig, + Qwen2_5OmniTalkerConfig, + Qwen2_5OmniTextConfig, + Qwen2_5OmniThinkerConfig, + Qwen2_5OmniToken2WavConfig, + Qwen2_5OmniVisionEncoderConfig, +) + + +logger = logging.get_logger(__name__) + + +def kaiser_sinc_filter1d(cutoff, half_width, kernel_size): + """Generates a 1D Kaiser-windowed sinc filter. + + Args: + cutoff (float): Normalized cutoff frequency (0 to 0.5). + half_width (float): Transition bandwidth. + kernel_size (int): Number of filter taps. + + Returns: + torch.Tensor: A tensor of shape (1, 1, kernel_size) representing the filter. + """ + is_even = kernel_size % 2 == 0 + half_size = kernel_size // 2 + + # Compute Kaiser window parameters + delta_f = 4 * half_width + attenuation = 2.285 * (half_size - 1) * math.pi * delta_f + 7.95 + + if attenuation > 50.0: + beta = 0.1102 * (attenuation - 8.7) + elif attenuation >= 21.0: + beta = 0.5842 * (attenuation - 21) ** 0.4 + 0.07886 * (attenuation - 21.0) + else: + beta = 0.0 + + kaiser_window = torch.kaiser_window(kernel_size, beta=beta, periodic=False, dtype=torch.float32) + + # Compute time indices + if is_even: + time_indices = torch.arange(-half_size, half_size) + 0.5 + else: + time_indices = torch.arange(kernel_size) - half_size + + # Compute sinc filter + if cutoff == 0: + return torch.zeros((1, 1, kernel_size), dtype=torch.float32) # Ensures correct shape + + sinc_filter = torch.sinc(2 * cutoff * time_indices) + normalized_filter = 2 * cutoff * kaiser_window * sinc_filter + + # Normalize to ensure sum = 1 (avoid leakage of constant component) + normalized_filter /= normalized_filter.sum() + + return normalized_filter.view(1, 1, kernel_size) + + +@auto_docstring +class Qwen2_5OmniPreTrainedModel(PreTrainedModel): + config: Qwen2_5OmniConfig + base_model_prefix = "model" + input_modalities = ("image", "video", "audio", "text") + supports_gradient_checkpointing = True + _no_split_modules = ["Qwen2_5OmniDecoderLayer", "Qwen2_5OmniVisionBlock"] + _skip_keys_device_placement = "past_key_values" + _supports_flash_attn = True + _supports_sdpa = True + _can_compile_fullgraph = False + _supports_attention_backend = True + + def _init_weights(self, module): + super()._init_weights(module) + if isinstance(module, SinusoidsPositionEmbedding): + log_timescale_increment = np.log(module.max_timescale) / (module.channels // 2 - 1) + inv_timescales = torch.exp(-log_timescale_increment * torch.arange(module.channels // 2).float()) + scaled_time = torch.arange(module.length)[:, np.newaxis] * inv_timescales[np.newaxis, :] + init.copy_(module.positional_embedding, torch.cat([torch.sin(scaled_time), torch.cos(scaled_time)], dim=1)) + elif isinstance(module, UpSample1d): + filter_tensor = kaiser_sinc_filter1d(0.5 / module.ratio, 0.6 / module.ratio, module.kernel_size) + init.copy_(module.filter, filter_tensor) + elif isinstance(module, DownSample1d): + filter_tensor = kaiser_sinc_filter1d(module.cutoff, module.half_width, module.kernel_size) + init.copy_(module.filter, filter_tensor) + elif isinstance(module, Qwen2_5_VisionRotaryEmbedding): + inv_freq = 1.0 / (module.theta ** (torch.arange(0, module.dim, 2, dtype=torch.float) / module.dim)) + init.copy_(module.inv_freq, inv_freq) + + +class Qwen2_5OmniPreTrainedModelForConditionalGeneration(Qwen2_5OmniPreTrainedModel): + input_modalities = ("image", "video", "audio", "text") + + def get_llm_pos_ids_for_vision( + self, + start_idx: int, + vision_idx: int, + spatial_merge_size: int, + t_index: list[int], + grid_hs: list[int], + grid_ws: list[int], + ): + llm_pos_ids_list = [] + llm_grid_h = grid_hs[vision_idx] // spatial_merge_size + llm_grid_w = grid_ws[vision_idx] // spatial_merge_size + h_index = torch.arange(llm_grid_h).view(1, -1, 1).expand(len(t_index), -1, llm_grid_w).flatten() + w_index = torch.arange(llm_grid_w).view(1, 1, -1).expand(len(t_index), llm_grid_h, -1).flatten() + t_index = torch.Tensor(t_index).view(-1, 1).expand(-1, llm_grid_h * llm_grid_w).flatten().long() + _llm_pos_ids = torch.stack([t_index, h_index, w_index]) + llm_pos_ids_list.append(_llm_pos_ids + start_idx) # + 1 ) # 12.09 by malinhan + llm_pos_ids = torch.cat(llm_pos_ids_list, dim=1) + return llm_pos_ids + + def get_chunked_index( + self, token_indices: torch.Tensor, tokens_per_chunk: int, remove_index: int + ) -> list[tuple[int, int]]: + """ + Splits token index list into chunks based on token value ranges. + + Given a list of token indices, returns a list of (start, end) index tuples representing + slices of the list where the token values fall within successive ranges of `t_ntoken_per_chunk`. + + For example, if `t_ntoken_per_chunk` is 1000, the function will create chunks such that: + - the first chunk contains token values < 1000, + - the second chunk contains values >= 1000 and < 2000, and so on. + + Parameters: + token_indices (`torch.Tensor` of shape `(seq_len, )`): A monotonically increasing list of + token index values. + t_ntoken_per_chunk (`int`): Number of tokens per chunk (used as the chunk size threshold). + remove_index (`int`) An index id to subtract from `token_indices` before chunking + + Returns: + `list[tuple[int, int]]`: A list of tuples, each representing the start (inclusive) + and end (exclusive) indices of a chunk in `token_indices`. + """ + + def _iter(): + i, start_idx = 0, 0 # skip bos token + current_chunk = 1 + while i < len(token_indices): # skip eos token + if token_indices[i] - remove_index >= current_chunk * tokens_per_chunk: + yield (start_idx, i) + start_idx = i + current_chunk += 1 + i += 1 + yield (start_idx, len(token_indices)) + + return list(_iter()) + + def get_rope_index( + self, + input_ids: torch.LongTensor | None = None, + image_grid_thw: torch.LongTensor | None = None, + video_grid_thw: torch.LongTensor | None = None, + attention_mask: torch.Tensor | None = None, + use_audio_in_video: bool = False, + audio_seqlens: torch.LongTensor | None = None, + second_per_grids: torch.Tensor | None = None, + ) -> tuple[torch.Tensor, torch.Tensor]: + """ + Calculate the 3D rope index based on image and video's temporal, height and width in LLM. + + Explanation: + Each embedding sequence contains vision embedding and text embedding or just contains text embedding. + + For pure text embedding sequence, the rotary position embedding has no difference with modern LLMs. + Examples: + input_ids: [T T T T T], here T is for text. + temporal position_ids: [0, 1, 2, 3, 4] + height position_ids: [0, 1, 2, 3, 4] + width position_ids: [0, 1, 2, 3, 4] + + For vision and text embedding sequence, we calculate 3D rotary position embedding for vision part + and 1D rotary position embedding for text part. + Examples: + Temporal (Time): 3 patches, representing different segments of the video in time. + Height: 2 patches, dividing each frame vertically. + Width: 2 patches, dividing each frame horizontally. + We also have some important parameters: + fps (Frames Per Second): The video's frame rate, set to 1. This means one frame is processed each second. + tokens_per_second: This is a crucial parameter. It dictates how many "time-steps" or "temporal tokens" are conceptually packed into a one-second interval of the video. In this case, we have 25 tokens per second. So each second of the video will be represented with 25 separate time points. It essentially defines the temporal granularity. + temporal_patch_size: The number of frames that compose one temporal patch. Here, it's 2 frames. + interval: The step size for the temporal position IDs, calculated as tokens_per_second * temporal_patch_size / fps. In this case, 25 * 2 / 1 = 50. This means that each temporal patch will be have a difference of 50 in the temporal position IDs. + input_ids: [V V V V V V V V V V V V T T T T T], here V is for vision. + vision temporal position_ids: [0, 0, 0, 0, 50, 50, 50, 50, 100, 100, 100, 100] + vision height position_ids: [0, 0, 1, 1, 0, 0, 1, 1, 0, 0, 1, 1] + vision width position_ids: [0, 1, 0, 1, 0, 1, 0, 1, 0, 1, 0, 1] + text temporal position_ids: [101, 102, 103, 104, 105] + text height position_ids: [101, 102, 103, 104, 105] + text width position_ids: [101, 102, 103, 104, 105] + Here we calculate the text start position_ids as the max vision position_ids plus 1. + + Args: + input_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`): + Indices of input sequence tokens in the vocabulary. Padding will be ignored by default should you provide + it. + image_grid_thw (`torch.LongTensor` of shape `(num_images, 3)`, *optional*): + The temporal, height and width of feature shape of each image in LLM. + video_grid_thw (`torch.LongTensor` of shape `(num_videos, 3)`, *optional*): + The temporal, height and width of feature shape of each video in LLM. + attention_mask (`torch.Tensor` of shape `(batch_size, sequence_length)`, *optional*): + Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`: + + - 1 for tokens that are **not masked**, + - 0 for tokens that are **masked**. + use_audio_in_video (`bool`, *optional*): + If set to `True`, use the audio in video. + audio_seqlens (`torch.LongTensor` of shape `(num_audios)`, *optional*): + The length of feature shape of each audio in LLM. + second_per_grids (`torch.LongTensor` of shape `(num_videos)`, *optional*): + The time interval (in seconds) for each grid along the temporal dimension in the 3D position IDs. + + Returns: + position_ids (`torch.LongTensor` of shape `(3, batch_size, sequence_length)`) + mrope_position_deltas (`torch.Tensor` of shape `(batch_size)`) + """ + spatial_merge_size = self.spatial_merge_size + image_token_id = self.config.image_token_id + video_token_id = self.config.video_token_id + audio_token_id = self.config.audio_token_id + vision_start_token_id = self.config.vision_start_token_id + audio_start_token_id = self.config.audio_start_token_id + position_id_per_seconds = self.config.position_id_per_seconds + seconds_per_chunk = self.config.seconds_per_chunk + + mrope_position_deltas = [] + if input_ids is not None and (image_grid_thw is not None or video_grid_thw is not None): + total_input_ids = input_ids + if attention_mask is not None: + attention_mask = attention_mask == 1 + position_ids = torch.ones( + 3, + input_ids.shape[0], + input_ids.shape[1], + dtype=input_ids.dtype, + device=input_ids.device, + ) + image_idx, video_idx, audio_idx = 0, 0, 0 + for i, input_ids in enumerate(total_input_ids): + if attention_mask is not None: + input_ids = input_ids[attention_mask[i]] + image_nums, video_nums, audio_nums = 0, 0, 0 + vision_start_indices = torch.argwhere(input_ids == vision_start_token_id).squeeze(1) + vision_tokens = input_ids[vision_start_indices + 1] + audio_nums = torch.sum(input_ids == audio_start_token_id) + image_nums = (vision_tokens == image_token_id).sum() + video_nums = ( + (vision_tokens == audio_start_token_id).sum() + if use_audio_in_video + else (vision_tokens == video_token_id).sum() + ) + input_tokens = input_ids.tolist() + llm_pos_ids_list: list = [] + st = 0 + remain_images, remain_videos, remain_audios = image_nums, video_nums, audio_nums + multimodal_nums = ( + image_nums + audio_nums if use_audio_in_video else image_nums + video_nums + audio_nums + ) + for _ in range(multimodal_nums): + st_idx = llm_pos_ids_list[-1].max() + 1 if len(llm_pos_ids_list) > 0 else 0 + if image_token_id in input_tokens and remain_images > 0: + ed_image = input_tokens.index(image_token_id, st) + else: + ed_image = len(input_tokens) + 1 + if video_token_id in input_tokens and remain_videos > 0: + ed_video = input_tokens.index(video_token_id, st) + else: + ed_video = len(input_tokens) + 1 + if audio_token_id in input_tokens and remain_audios > 0: + ed_audio = input_tokens.index(audio_token_id, st) + else: + ed_audio = len(input_tokens) + 1 + min_ed = min(ed_image, ed_video, ed_audio) + if min_ed == ed_audio: + text_len = min_ed - st - 1 + if text_len != 0: + st_idx = llm_pos_ids_list[-1].max() + 1 if len(llm_pos_ids_list) > 0 else 0 + llm_pos_ids_list.append(torch.arange(text_len).view(1, -1).expand(3, -1) + st_idx) + + st_idx = llm_pos_ids_list[-1].max() + 1 if len(llm_pos_ids_list) > 0 else 0 + bos_len = 1 + llm_pos_ids_list.append(torch.arange(bos_len).view(1, -1).expand(3, -1) + st_idx) + + st_idx = llm_pos_ids_list[-1].max() + 1 if len(llm_pos_ids_list) > 0 else 0 + audio_len = ((audio_seqlens[audio_idx] - 1) // 2 + 1 - 2) // 2 + 1 + llm_pos_ids = torch.arange(audio_len).view(1, -1).expand(3, -1) + st_idx + llm_pos_ids_list.append(llm_pos_ids) + + st_idx = llm_pos_ids_list[-1].max() + 1 if len(llm_pos_ids_list) > 0 else 0 + eos_len = 1 + llm_pos_ids_list.append(torch.arange(eos_len).view(1, -1).expand(3, -1) + st_idx) + + st += text_len + bos_len + audio_len + eos_len + audio_idx += 1 + remain_audios -= 1 + + elif min_ed == ed_image: + text_len = min_ed - st - 1 + if text_len != 0: + st_idx = llm_pos_ids_list[-1].max() + 1 if len(llm_pos_ids_list) > 0 else 0 + llm_pos_ids_list.append(torch.arange(text_len).view(1, -1).expand(3, -1) + st_idx) + + st_idx = llm_pos_ids_list[-1].max() + 1 if len(llm_pos_ids_list) > 0 else 0 + bos_len = 1 + llm_pos_ids_list.append(torch.arange(bos_len).view(1, -1).expand(3, -1) + st_idx) + + st_idx = llm_pos_ids_list[-1].max() + 1 if len(llm_pos_ids_list) > 0 else 0 + grid_t = image_grid_thw[image_idx][0] + grid_hs = image_grid_thw[:, 1] + grid_ws = image_grid_thw[:, 2] + t_index = (torch.arange(grid_t) * 1 * position_id_per_seconds).long() + llm_pos_ids = self.get_llm_pos_ids_for_vision( + st_idx, image_idx, spatial_merge_size, t_index, grid_hs, grid_ws + ) + image_len = image_grid_thw[image_idx].prod() // (spatial_merge_size**2) + llm_pos_ids_list.append(llm_pos_ids) + + st_idx = llm_pos_ids_list[-1].max() + 1 if len(llm_pos_ids_list) > 0 else 0 + eos_len = 1 + llm_pos_ids_list.append(torch.arange(eos_len).view(1, -1).expand(3, -1) + st_idx) + + st += text_len + bos_len + image_len + eos_len + image_idx += 1 + remain_images -= 1 + + elif min_ed == ed_video and not use_audio_in_video: + text_len = min_ed - st - 1 + if text_len != 0: + st_idx = llm_pos_ids_list[-1].max() + 1 if len(llm_pos_ids_list) > 0 else 0 + llm_pos_ids_list.append(torch.arange(text_len).view(1, -1).expand(3, -1) + st_idx) + + st_idx = llm_pos_ids_list[-1].max() + 1 if len(llm_pos_ids_list) > 0 else 0 + bos_len = 1 + llm_pos_ids_list.append(torch.arange(bos_len).view(1, -1).expand(3, -1) + st_idx) + + st_idx = llm_pos_ids_list[-1].max() + 1 if len(llm_pos_ids_list) > 0 else 0 + grid_t = video_grid_thw[video_idx][0] + grid_hs = video_grid_thw[:, 1] + grid_ws = video_grid_thw[:, 2] + t_index = ( + torch.arange(grid_t) * second_per_grids[video_idx].cpu().float() * position_id_per_seconds + ).long() + llm_pos_ids = self.get_llm_pos_ids_for_vision( + st_idx, video_idx, spatial_merge_size, t_index, grid_hs, grid_ws + ) + video_len = video_grid_thw[video_idx].prod() // (spatial_merge_size**2) + llm_pos_ids_list.append(llm_pos_ids) + + st_idx = llm_pos_ids_list[-1].max() + 1 if len(llm_pos_ids_list) > 0 else 0 + eos_len = 1 + llm_pos_ids_list.append(torch.arange(eos_len).view(1, -1).expand(3, -1) + st_idx) + + st += text_len + bos_len + video_len + eos_len + video_idx += 1 + remain_videos -= 1 + + elif min_ed == ed_video and use_audio_in_video: + text_len = min_ed - st - 2 + if text_len != 0: + st_idx = llm_pos_ids_list[-1].max() + 1 if len(llm_pos_ids_list) > 0 else 0 + llm_pos_ids_list.append(torch.arange(text_len).view(1, -1).expand(3, -1) + st_idx) + + st_idx = llm_pos_ids_list[-1].max() + 1 if len(llm_pos_ids_list) > 0 else 0 + bos_len = 1 + llm_pos_ids_list.append(torch.arange(bos_len).view(1, -1).expand(3, -1) + st_idx) + llm_pos_ids_list.append(torch.arange(bos_len).view(1, -1).expand(3, -1) + st_idx) + + st_idx = llm_pos_ids_list[-1].max() + 1 if len(llm_pos_ids_list) > 0 else 0 + audio_len = ((audio_seqlens[audio_idx] - 1) // 2 + 1 - 2) // 2 + 1 + audio_llm_pos_ids = torch.arange(audio_len).view(1, -1).expand(3, -1) + st_idx + grid_t = video_grid_thw[video_idx][0] + grid_hs = video_grid_thw[:, 1] + grid_ws = video_grid_thw[:, 2] + + t_index = ( + torch.arange(grid_t) * second_per_grids[video_idx].cpu().float() * position_id_per_seconds + ).long() + video_llm_pos_ids = self.get_llm_pos_ids_for_vision( + st_idx, video_idx, spatial_merge_size, t_index, grid_hs, grid_ws + ) + + t_ntoken_per_chunk = int(position_id_per_seconds * seconds_per_chunk) + video_chunk_indexes = self.get_chunked_index(video_llm_pos_ids[0], t_ntoken_per_chunk, st_idx) + audio_chunk_indexes = self.get_chunked_index(audio_llm_pos_ids[0], t_ntoken_per_chunk, st_idx) + sub_len = 0 + for j in range(max(len(video_chunk_indexes), len(audio_chunk_indexes))): + video_chunk_index = video_chunk_indexes[j] if j < len(video_chunk_indexes) else None + audio_chunk_index = audio_chunk_indexes[j] if j < len(audio_chunk_indexes) else None + if video_chunk_index is not None: + sub_len += video_chunk_index[1] - video_chunk_index[0] + + llm_pos_ids_list.append( + video_llm_pos_ids[:, video_chunk_index[0] : video_chunk_index[1]] + ) + if audio_chunk_index is not None: + sub_len += audio_chunk_index[1] - audio_chunk_index[0] + + llm_pos_ids_list.append( + audio_llm_pos_ids[:, audio_chunk_index[0] : audio_chunk_index[1]] + ) + video_len = video_grid_thw[video_idx].prod() // (spatial_merge_size**2) + + st_idx = llm_pos_ids_list[-1].max() + 1 if len(llm_pos_ids_list) > 0 else 0 + eos_len = 1 + llm_pos_ids_list.append(torch.arange(eos_len).view(1, -1).expand(3, -1) + st_idx) + llm_pos_ids_list.append(torch.arange(eos_len).view(1, -1).expand(3, -1) + st_idx) + + st += text_len + bos_len * 2 + audio_len + video_len + eos_len * 2 + + audio_idx += 1 + video_idx += 1 + remain_videos -= 1 + remain_audios -= 1 + + if st < len(input_tokens): + st_idx = llm_pos_ids_list[-1].max() + 1 if len(llm_pos_ids_list) > 0 else 0 + text_len = len(input_tokens) - st + llm_pos_ids_list.append(torch.arange(text_len).view(1, -1).expand(3, -1) + st_idx) + + llm_positions = torch.cat(llm_pos_ids_list, dim=1).reshape(3, -1) + + if attention_mask is not None: + position_ids[..., i, attention_mask[i]] = llm_positions.to(position_ids.device) + else: + position_ids[..., i, :] = llm_positions.to(position_ids.device) + mrope_position_deltas.append(llm_positions.max() + 1 - len(input_ids)) + mrope_position_deltas = torch.tensor(mrope_position_deltas).unsqueeze(1).to(device=input_ids.device) + + return position_ids, mrope_position_deltas + else: + position_ids = attention_mask.long().cumsum(-1) - 1 + position_ids.masked_fill_(attention_mask == 0, 1) + position_ids = position_ids.unsqueeze(0).expand(3, -1, -1).to(attention_mask.device) + max_position_ids = position_ids.max(0, keepdim=False)[0].max(-1, keepdim=True)[0] + mrope_position_deltas = max_position_ids + 1 - torch.sum(attention_mask, dim=-1, keepdim=True) + + return position_ids, mrope_position_deltas + + +############################ +# Start Thinker # +############################ + + +@dataclass +@auto_docstring( + custom_intro=""" + Base class for Qwen2.5OmniThinker causal language model (or autoregressive) outputs. + """ +) +class Qwen2_5OmniThinkerCausalLMOutputWithPast(ModelOutput): + r""" + loss (`torch.FloatTensor` of shape `(1,)`, *optional*, returned when `labels` is provided): + Language modeling loss (for next-token prediction). + logits (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.vocab_size)`, *optional*): + Prediction scores of the language modeling head (scores for each vocabulary token before SoftMax). + past_key_values (`Cache`, *optional*, returned when `use_cache=True` is passed or when `config.use_cache=True`): + It is a [`~cache_utils.Cache`] instance. For more details, see our [kv cache guide](https://huggingface.co/docs/transformers/en/kv_cache). + + Contains pre-computed hidden-states (key and values in the self-attention blocks) that can be used (see + `past_key_values` input) to speed up sequential decoding. + rope_deltas (`torch.LongTensor` of shape `(batch_size, )`, *optional*): + The rope index difference between sequence length and multimodal rope. + """ + + loss: torch.FloatTensor | None = None + logits: torch.FloatTensor | None = None + past_key_values: Cache | None = None + hidden_states: tuple[torch.FloatTensor] | None = None + attentions: tuple[torch.FloatTensor] | None = None + rope_deltas: torch.LongTensor | None = None + + +def repeat_kv(hidden_states: torch.Tensor, n_rep: int) -> torch.Tensor: + """ + This is the equivalent of torch.repeat_interleave(x, dim=1, repeats=n_rep). The hidden states go from (batch, + num_key_value_heads, seqlen, head_dim) to (batch, num_attention_heads, seqlen, head_dim) + """ + batch, num_key_value_heads, slen, head_dim = hidden_states.shape + if n_rep == 1: + return hidden_states + hidden_states = hidden_states[:, :, None, :, :].expand(batch, num_key_value_heads, n_rep, slen, head_dim) + return hidden_states.reshape(batch, num_key_value_heads * n_rep, slen, head_dim) + + +def eager_attention_forward( + module: nn.Module, + query: torch.Tensor, + key: torch.Tensor, + value: torch.Tensor, + attention_mask: torch.Tensor | None, + scaling: float, + dropout: float = 0.0, + **kwargs, +): + key_states = repeat_kv(key, module.num_key_value_groups) + value_states = repeat_kv(value, module.num_key_value_groups) + + attn_weights = torch.matmul(query, key_states.transpose(2, 3)) * scaling + if attention_mask is not None: + attn_weights = attn_weights + attention_mask + + attn_weights = nn.functional.softmax(attn_weights, dim=-1, dtype=torch.float32).to(query.dtype) + attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training) + attn_output = torch.matmul(attn_weights, value_states) + attn_output = attn_output.transpose(1, 2).contiguous() + + return attn_output, attn_weights + + +class Qwen2_5OmniAudioAttention(nn.Module): + """Multi-headed attention from 'Attention Is All You Need' paper""" + + def __init__( + self, + config: Qwen2_5OmniAudioEncoderConfig, + ): + super().__init__() + self.embed_dim = config.d_model + self.num_heads = config.encoder_attention_heads + self.dropout = config.attention_dropout + self.head_dim = self.embed_dim // self.num_heads + self.num_key_value_groups = 1 # needed for eager attention + self.config = config + + if (self.head_dim * self.num_heads) != self.embed_dim: + raise ValueError( + f"embed_dim must be divisible by num_heads (got `embed_dim`: {self.embed_dim}" + f" and `num_heads`: {self.num_heads})." + ) + self.scaling = self.head_dim**-0.5 + self.attention_dropout = 0.0 + self.is_decoder = False + self.is_causal = False + + self.k_proj = nn.Linear(self.embed_dim, self.embed_dim, bias=False) + self.v_proj = nn.Linear(self.embed_dim, self.embed_dim, bias=True) + self.q_proj = nn.Linear(self.embed_dim, self.embed_dim, bias=True) + self.out_proj = nn.Linear(self.embed_dim, self.embed_dim, bias=True) + + def forward( + self, + hidden_states: torch.Tensor, + cu_seqlens: torch.Tensor | None = None, + attention_mask: torch.Tensor | None = None, + **kwargs, + ) -> tuple[torch.Tensor, torch.Tensor | None, tuple[torch.Tensor] | None]: + """Input shape: Batch x Time x Channel""" + + seq_length, _ = hidden_states.size() + + query_states = self.q_proj(hidden_states).reshape(seq_length, self.num_heads, -1) + key_states = self.k_proj(hidden_states).reshape(seq_length, self.num_heads, -1) + value_states = self.v_proj(hidden_states).reshape(seq_length, self.num_heads, -1) + + query_states = query_states.transpose(0, 1).unsqueeze(0) + key_states = key_states.transpose(0, 1).unsqueeze(0) + value_states = value_states.transpose(0, 1).unsqueeze(0) + max_seqlen = (cu_seqlens[1:] - cu_seqlens[:-1]).max() + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, eager_attention_forward + ) + + attn_output, _ = attention_interface( + self, + query_states, + key_states, + value_states, + attention_mask=attention_mask, + dropout=0.0 if not self.training else self.attention_dropout, + scaling=self.scaling, + cu_seq_lens_q=cu_seqlens, # pass cu seq lens for FA2 + cu_seq_lens_k=cu_seqlens, + max_length_q=max_seqlen, + max_length_k=max_seqlen, + is_causal=False, + **kwargs, + ) + + attn_output = attn_output.reshape(seq_length, -1).contiguous() + attn_output = self.out_proj(attn_output) + + return attn_output + + +class Qwen2_5OmniAudioEncoderLayer(GradientCheckpointingLayer): + def __init__(self, config: Qwen2_5OmniAudioEncoderConfig): + super().__init__() + self.embed_dim = config.d_model + self.self_attn = Qwen2_5OmniAudioAttention(config) + self.self_attn_layer_norm = nn.LayerNorm(self.embed_dim) + self.dropout = config.dropout + self.activation_fn = ACT2FN[config.activation_function] + self.activation_dropout = config.activation_dropout + self.fc1 = nn.Linear(self.embed_dim, config.encoder_ffn_dim) + self.fc2 = nn.Linear(config.encoder_ffn_dim, self.embed_dim) + self.final_layer_norm = nn.LayerNorm(self.embed_dim) + + def forward( + self, + hidden_states: torch.Tensor, + cu_seqlens: torch.Tensor, + attention_mask: torch.Tensor | None = None, + **kwargs, + ) -> torch.Tensor: + """ + Args: + hidden_states (`torch.FloatTensor`): input to the layer of shape `(batch, seq_len, embed_dim)` + attention_mask (`torch.FloatTensor`): attention mask of size + `(batch, 1, tgt_len, src_len)` where padding elements are indicated by very large negative values. + output_attentions (`bool`, *optional*): + Whether or not to return the attentions tensors of all attention layers. See `attentions` under + returned tensors for more detail. + """ + residual = hidden_states + hidden_states = self.self_attn_layer_norm(hidden_states) + hidden_states = self.self_attn( + hidden_states=hidden_states, + cu_seqlens=cu_seqlens, + attention_mask=attention_mask, + **kwargs, + ) + hidden_states = residual + hidden_states + residual = hidden_states + hidden_states = self.final_layer_norm(hidden_states) + hidden_states = self.fc1(hidden_states) + hidden_states = self.activation_fn(hidden_states) + hidden_states = self.fc2(hidden_states) + hidden_states = residual + hidden_states + + if hidden_states.dtype == torch.float16: + clamp_value = torch.finfo(hidden_states.dtype).max - 1000 + hidden_states = torch.clamp(hidden_states, min=-clamp_value, max=clamp_value) + + outputs = (hidden_states,) + + return outputs + + +class SinusoidsPositionEmbedding(nn.Module): + def __init__(self, length, channels, max_timescale=10000): + super().__init__() + self.length = length + self.channels = channels + self.max_timescale = max_timescale + if channels % 2 != 0: + raise ValueError("SinusoidsPositionEmbedding needs even channels input") + log_timescale_increment = np.log(max_timescale) / (channels // 2 - 1) + inv_timescales = torch.exp(-log_timescale_increment * torch.arange(channels // 2).float()) + scaled_time = torch.arange(length)[:, np.newaxis] * inv_timescales[np.newaxis, :] + self.register_buffer( + "positional_embedding", + torch.cat([torch.sin(scaled_time), torch.cos(scaled_time)], dim=1), + persistent=False, + ) + + def forward(self, seqlen: int): + return self.positional_embedding[:seqlen, :] + + +@auto_docstring( + custom_intro=""" + Transformer encoder consisting of *config.encoder_layers* self attention layers. Each layer is a + [`Qwen2_5OmniAudioEncoderLayer`]. + """ +) +class Qwen2_5OmniAudioEncoder(Qwen2_5OmniPreTrainedModel): + config: Qwen2_5OmniAudioEncoderConfig + main_input_name = "input_features" + input_modalities = "audio" + _no_split_modules = ["Qwen2_5OmniAudioEncoderLayer"] + _supports_sdpa = True + _can_record_outputs = { + "hidden_states": Qwen2_5OmniAudioEncoderLayer, + "attentions": Qwen2_5OmniAudioAttention, + } + + def __init__(self, config: Qwen2_5OmniAudioEncoderConfig): + super().__init__(config) + self.dropout = config.dropout + + embed_dim = config.d_model + self.num_mel_bins = config.num_mel_bins + self.max_source_positions = config.max_source_positions + self.embed_scale = math.sqrt(embed_dim) if config.scale_embedding else 1.0 + self.n_window = config.n_window + self.conv1 = nn.Conv1d(self.num_mel_bins, embed_dim, kernel_size=3, padding=1) + self.conv2 = nn.Conv1d(embed_dim, embed_dim, kernel_size=3, stride=2, padding=1) + self.positional_embedding = SinusoidsPositionEmbedding(self.max_source_positions, embed_dim) + self.audio_bos_eos_token = nn.Embedding(2, config.output_dim) + self.layers = nn.ModuleList([Qwen2_5OmniAudioEncoderLayer(config) for _ in range(config.encoder_layers)]) + self.ln_post = nn.LayerNorm(config.d_model) + self.avg_pooler = nn.AvgPool1d(2, stride=2) + self.proj = nn.Linear(config.d_model, config.output_dim) + self.gradient_checkpointing = False + # Initialize weights and apply final processing + self.post_init() + + def _freeze_parameters(self): + for param in self.parameters(): + param.requires_grad = False + self._requires_grad = False + + def get_input_embeddings(self) -> nn.Module: + return self.conv1 + + def set_input_embeddings(self, value: nn.Module): + self.conv1 = value + + def _prepare_attention_mask(self, inputs_tensor: torch.Tensor, cu_seqlens: torch.Tensor) -> torch.Tensor: + # Flash Attention 2 doesn't need a 4D mask and relies on `cu_seqlens/max_seqlen` + # NOTE: the created attention masl only approximates the ragged FA2 attention by + # allowing bidirectional attention within `cu_seqlens` blocks, and not attending between + # blocks. Though it will not be a 100% match for FA2's `varlen` path + if is_flash_attention_requested(self.config): + return None + + seq_length = inputs_tensor.shape[0] + attention_mask = torch.full( + [1, 1, seq_length, seq_length], + torch.finfo(inputs_tensor.dtype).min, + device=inputs_tensor.device, + dtype=inputs_tensor.dtype, + ) + for i in range(1, len(cu_seqlens)): + attention_mask[..., cu_seqlens[i - 1] : cu_seqlens[i], cu_seqlens[i - 1] : cu_seqlens[i]] = 0 + return attention_mask + + @merge_with_config_defaults + @capture_outputs(tie_last_hidden_states=False) + @auto_docstring + def forward(self, input_features, feature_lens=None, aftercnn_lens=None, **kwargs: Unpack[TransformersKwargs]): + r""" + feature_lens (`torch.LongTensor` of shape `(batch_size,)`): + mel length + aftercnn_lens (`torch.LongTensor` of shape `(batch_size,)`): + mel length after cnn + """ + chunk_num = torch.ceil(feature_lens / (self.n_window * 2)).long() + + chunk_lengths = torch.full((chunk_num.sum(),), self.n_window * 2, dtype=torch.long, device=feature_lens.device) + tail_chunk_index = F.pad(chunk_num, (1, 0), value=-1).cumsum(0)[1:] + chunk_lengths[tail_chunk_index] = feature_lens % (self.n_window * 2) + chunk_lengths = torch.where(chunk_lengths == 0, self.n_window * 2, chunk_lengths) + + chunk_list = input_features.split(chunk_lengths.tolist(), dim=1) + padded_feature, padded_mask, padded_mask_after_cnn = self.padded_and_mask_function( + chunk_list, chunk_lengths, padding_value=0, padding_side="right" + ) + padded_embed = nn.functional.gelu(self.conv1(padded_feature)) * padded_mask + padded_embed = nn.functional.gelu(self.conv2(padded_embed)).transpose(1, 2) + + padded_embed = padded_embed + self.positional_embedding.positional_embedding[ + : padded_embed.shape[1], : + ].unsqueeze(0).to(padded_embed.dtype) + hidden_states = padded_embed[padded_mask_after_cnn] + cu_seqlens = torch.cat( + ( + torch.zeros(1, device=padded_mask_after_cnn.device, dtype=torch.int32), + padded_mask_after_cnn.sum(1).cumsum(0), + ) + ).to(torch.int32) + attention_mask = self._prepare_attention_mask(hidden_states, cu_seqlens) + + for encoder_layer in self.layers: + layer_outputs = encoder_layer( + hidden_states, + cu_seqlens=cu_seqlens, + attention_mask=attention_mask, + **kwargs, + ) + hidden_states = layer_outputs[0] + + hidden_states_list = hidden_states.split(aftercnn_lens.tolist(), dim=0) + token_audio_list = [] + for each_audio_states in hidden_states_list: + each_audio_states = self.avg_pooler(each_audio_states.transpose(0, 1)).transpose_(0, 1) + each_audio_states = self.ln_post(each_audio_states) + each_audio_states = self.proj(each_audio_states) + token_audio_list.append(each_audio_states) + token_audio = torch.cat(token_audio_list, dim=0) + return BaseModelOutputWithPooling(last_hidden_state=token_audio) + + def padded_and_mask_function(self, tensor_list, tensor_len, padding_value=0, padding_side="right"): + """ + Pads a sequence of tensors to their maximum length on indicated `padding_side`. + Then prepares a mask so that pad tokens are not attended to. + """ + max_len = tensor_len.max() + dim = tensor_list[0].shape[0] + padded_tensor = torch.full( + size=(len(tensor_list), dim, max_len), + fill_value=padding_value, + dtype=self.dtype, + device=tensor_list[0].device, + ) + + batch_mask = torch.zeros( + (len(tensor_len), max_len), + dtype=torch.long, + device=padded_tensor.device, + ) + for i, length in enumerate(tensor_len): + batch_mask[i, :length] = 1 + padded_tensor[i, :, :length] = tensor_list[i] + + feature_lens_after_cnn = (tensor_len - 1) // 2 + 1 + max_len_after_cnn = feature_lens_after_cnn.max() + batch_mask_after_cnn = torch.zeros( + (len(tensor_len), max_len_after_cnn), + dtype=torch.long, + device=padded_tensor.device, + ) + for i, length in enumerate(feature_lens_after_cnn): + batch_mask_after_cnn[i, :length] = 1 + return ( + padded_tensor, + batch_mask.unsqueeze(1), + batch_mask_after_cnn.bool(), + ) + + # Ignore copy + def _get_feat_extract_output_lengths(self, input_lengths: torch.LongTensor): + """ + Computes the output length of the convolutional layers and the output length of the audio encoder + """ + input_lengths = (input_lengths - 1) // 2 + 1 + output_lengths = (input_lengths - 2) // 2 + 1 + return input_lengths, output_lengths + + +def rotate_half(x): + """Rotates half the hidden dims of the input.""" + x1 = x[..., : x.shape[-1] // 2] + x2 = x[..., x.shape[-1] // 2 :] + return torch.cat((-x2, x1), dim=-1) + + +def apply_rotary_pos_emb_vision(tensor: torch.Tensor, freqs: torch.Tensor) -> torch.Tensor: + orig_dtype = tensor.dtype + tensor = tensor.float() + cos = freqs.cos() + sin = freqs.sin() + cos = cos.unsqueeze(1).repeat(1, 1, 2).unsqueeze(0).float() + sin = sin.unsqueeze(1).repeat(1, 1, 2).unsqueeze(0).float() + output = (tensor * cos) + (rotate_half(tensor) * sin) + output = output.to(orig_dtype) + return output + + +class Qwen2_5OmniVisionAttention(nn.Module): + def __init__(self, config: Qwen2_5OmniVisionEncoderConfig = None) -> None: + super().__init__() + self.dim = config.hidden_size + self.num_heads = config.num_heads + self.head_dim = self.dim // self.num_heads + self.q = nn.Linear(self.dim, self.dim, bias=True) + self.k = nn.Linear(self.dim, self.dim, bias=True) + self.v = nn.Linear(self.dim, self.dim, bias=True) + self.proj = nn.Linear(self.dim, self.dim) + self.scaling = self.head_dim**-0.5 + self.num_key_value_groups = 1 # needed for eager attention + self.config = config + self.attention_dropout = 0.0 + self.is_causal = False + + def forward( + self, + hidden_states: torch.Tensor, + cu_seqlens: torch.Tensor, + rotary_pos_emb: torch.Tensor | None = None, + **kwargs, + ) -> torch.Tensor: + seq_length = hidden_states.shape[0] + query_states = self.q(hidden_states).reshape(seq_length, self.num_heads, -1) + key_states = self.k(hidden_states).reshape(seq_length, self.num_heads, -1) + value_states = self.v(hidden_states).reshape(seq_length, self.num_heads, -1) + query_states = apply_rotary_pos_emb_vision(query_states.unsqueeze(0), rotary_pos_emb).squeeze(0) + key_states = apply_rotary_pos_emb_vision(key_states.unsqueeze(0), rotary_pos_emb).squeeze(0) + + query_states = query_states.transpose(0, 1).unsqueeze(0) + key_states = key_states.transpose(0, 1).unsqueeze(0) + value_states = value_states.transpose(0, 1).unsqueeze(0) + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, eager_attention_forward + ) + + if is_flash_attention_requested(self.config): + # Flash Attention 2: Use cu_seqlens for variable length attention + max_seqlen = (cu_seqlens[1:] - cu_seqlens[:-1]).max() + attn_output, _ = attention_interface( + self, + query_states, + key_states, + value_states, + attention_mask=None, + scaling=self.scaling, + dropout=0.0 if not self.training else self.attention_dropout, + cu_seq_lens_q=cu_seqlens, + cu_seq_lens_k=cu_seqlens, + max_length_q=max_seqlen, + max_length_k=max_seqlen, + is_causal=False, + **kwargs, + ) + else: + # Other implementations: Process each chunk separately + lengths = cu_seqlens[1:] - cu_seqlens[:-1] + splits = [ + torch.split(tensor, lengths.tolist(), dim=2) for tensor in (query_states, key_states, value_states) + ] + + attn_outputs = [ + attention_interface( + self, + q, + k, + v, + attention_mask=None, + scaling=self.scaling, + dropout=0.0 if not self.training else self.attention_dropout, + is_causal=False, + **kwargs, + )[0] + for q, k, v in zip(*splits) + ] + attn_output = torch.cat(attn_outputs, dim=1) + + attn_output = attn_output.reshape(seq_length, -1).contiguous() + attn_output = self.proj(attn_output) + return attn_output + + +@use_kernel_forward_from_hub("RMSNorm") +class Qwen2_5OmniRMSNorm(nn.Module): + def __init__(self, hidden_size, eps: float = 1e-6) -> None: + """ + Qwen2_5OmniRMSNorm is equivalent to T5LayerNorm + """ + super().__init__() + self.weight = nn.Parameter(torch.ones(hidden_size)) + self.variance_epsilon = eps + + def forward(self, hidden_states: torch.Tensor) -> torch.Tensor: + input_dtype = hidden_states.dtype + hidden_states = hidden_states.to(torch.float32) + variance = hidden_states.pow(2).mean(-1, keepdim=True) + hidden_states = hidden_states * torch.rsqrt(variance + self.variance_epsilon) + return self.weight * hidden_states.to(input_dtype) + + def extra_repr(self): + return f"{tuple(self.weight.shape)}, eps={self.variance_epsilon}" + + +class Qwen2_5OmniMLP(nn.Module): + def __init__(self, config, bias: bool = False): + super().__init__() + self.hidden_size = config.hidden_size + self.intermediate_size = config.intermediate_size + self.gate_proj = nn.Linear(self.hidden_size, self.intermediate_size, bias=bias) + self.up_proj = nn.Linear(self.hidden_size, self.intermediate_size, bias=bias) + self.down_proj = nn.Linear(self.intermediate_size, self.hidden_size, bias=bias) + self.act_fn = ACT2FN[config.hidden_act] + + def forward(self, hidden_state): + return self.down_proj(self.act_fn(self.gate_proj(hidden_state)) * self.up_proj(hidden_state)) + + +class Qwen2_5OmniVisionBlock(GradientCheckpointingLayer): + def __init__(self, config: Qwen2_5OmniVisionEncoderConfig) -> None: + super().__init__() + self.norm1 = Qwen2_5OmniRMSNorm(config.hidden_size, eps=1e-6) + self.norm2 = Qwen2_5OmniRMSNorm(config.hidden_size, eps=1e-6) + self.attn = Qwen2_5OmniVisionAttention(config=config) + self.mlp = Qwen2_5OmniMLP(config, bias=True) + + def forward( + self, + hidden_states: torch.Tensor, + cu_seqlens: torch.Tensor, + rotary_pos_emb: torch.Tensor | None = None, + **kwargs, + ) -> torch.Tensor: + hidden_states = hidden_states + self.attn( + self.norm1(hidden_states), + cu_seqlens=cu_seqlens, + rotary_pos_emb=rotary_pos_emb, + **kwargs, + ) + hidden_states = hidden_states + self.mlp(self.norm2(hidden_states)) + return hidden_states + + +class Qwen2_5_VisionRotaryEmbedding(nn.Module): + inv_freq: torch.Tensor # fix linting for `register_buffer` + + def __init__(self, dim: int, theta: float = 10000.0) -> None: + super().__init__() + self.dim = dim + self.theta = theta + inv_freq = 1.0 / (theta ** (torch.arange(0, dim, 2, dtype=torch.float) / dim)) + self.register_buffer("inv_freq", inv_freq, persistent=False) + + def forward(self, seqlen: int) -> torch.Tensor: + seq = torch.arange(seqlen, device=self.inv_freq.device, dtype=self.inv_freq.dtype) + freqs = torch.outer(seq, self.inv_freq) + return freqs + + +class Qwen2_5_VisionPatchEmbed(nn.Module): + def __init__( + self, + patch_size: int = 14, + temporal_patch_size: int = 2, + in_channels: int = 3, + embed_dim: int = 1152, + ) -> None: + super().__init__() + self.patch_size = patch_size + self.temporal_patch_size = temporal_patch_size + self.in_channels = in_channels + self.embed_dim = embed_dim + + kernel_size = [temporal_patch_size, patch_size, patch_size] + self.proj = nn.Conv3d(in_channels, embed_dim, kernel_size=kernel_size, stride=kernel_size, bias=False) + + def forward(self, hidden_states: torch.Tensor) -> torch.Tensor: + target_dtype = self.proj.weight.dtype + hidden_states = hidden_states.view( + -1, self.in_channels, self.temporal_patch_size, self.patch_size, self.patch_size + ) + hidden_states = self.proj(hidden_states.to(dtype=target_dtype)).view(-1, self.embed_dim) + return hidden_states + + +class Qwen2_5OmniPatchMerger(nn.Module): + def __init__(self, dim: int, context_dim: int, spatial_merge_size: int = 2) -> None: + super().__init__() + self.hidden_size = context_dim * (spatial_merge_size**2) + self.ln_q = Qwen2_5OmniRMSNorm(context_dim, eps=1e-6) + self.mlp = nn.Sequential( + nn.Linear(self.hidden_size, self.hidden_size), + nn.GELU(), + nn.Linear(self.hidden_size, dim), + ) + + def forward(self, x: torch.Tensor) -> torch.Tensor: + x = self.mlp(self.ln_q(x).view(-1, self.hidden_size)) + return x + + +class Qwen2_5OmniVisionEncoder(Qwen2_5OmniPreTrainedModel): + config: Qwen2_5OmniVisionEncoderConfig + _no_split_modules = ["Qwen2_5OmniVisionBlock"] + _input_embed_layer = "patch_embed" + _can_record_outputs = { + "hidden_states": Qwen2_5OmniVisionBlock, + "attentions": Qwen2_5OmniVisionAttention, + } + input_modalities = ("image", "video") + + def __init__(self, config: Qwen2_5OmniVisionEncoderConfig, *inputs, **kwargs) -> None: + super().__init__(config, *inputs, **kwargs) + self.spatial_merge_size = config.spatial_merge_size + self.patch_size = config.patch_size + self.fullatt_block_indexes = config.fullatt_block_indexes + self.window_size = config.window_size + self.spatial_merge_unit = self.spatial_merge_size * self.spatial_merge_size + + self.patch_embed = Qwen2_5_VisionPatchEmbed( + patch_size=config.patch_size, + temporal_patch_size=config.temporal_patch_size, + in_channels=config.in_channels, + embed_dim=config.hidden_size, + ) + + head_dim = config.hidden_size // config.num_heads + self.rotary_pos_emb = Qwen2_5_VisionRotaryEmbedding(head_dim // 2) + self.blocks = nn.ModuleList([Qwen2_5OmniVisionBlock(config) for _ in range(config.depth)]) + self.merger = Qwen2_5OmniPatchMerger( + dim=config.out_hidden_size, + context_dim=config.hidden_size, + spatial_merge_size=config.spatial_merge_size, + ) + self.gradient_checkpointing = False + + self.post_init() + + def rot_pos_emb(self, grid_thw): + pos_ids = [] + for t, h, w in grid_thw.tolist(): + hpos_ids = torch.arange(h).unsqueeze(1).expand(-1, w) + hpos_ids = hpos_ids.reshape( + h // self.spatial_merge_size, + self.spatial_merge_size, + w // self.spatial_merge_size, + self.spatial_merge_size, + ) + hpos_ids = hpos_ids.permute(0, 2, 1, 3) + hpos_ids = hpos_ids.flatten() + + wpos_ids = torch.arange(w).unsqueeze(0).expand(h, -1) + wpos_ids = wpos_ids.reshape( + h // self.spatial_merge_size, + self.spatial_merge_size, + w // self.spatial_merge_size, + self.spatial_merge_size, + ) + wpos_ids = wpos_ids.permute(0, 2, 1, 3) + wpos_ids = wpos_ids.flatten() + pos_ids.append(torch.stack([hpos_ids, wpos_ids], dim=-1).repeat(t, 1)) + pos_ids = torch.cat(pos_ids, dim=0) + max_grid_size = grid_thw[:, 1:].max() + rotary_pos_emb_full = self.rotary_pos_emb(max_grid_size) + rotary_pos_emb = rotary_pos_emb_full[pos_ids].flatten(1) + return rotary_pos_emb + + def get_window_index(self, grid_thw): + window_index: list = [] + cu_window_seqlens: list = [0] + window_index_id = 0 + vit_merger_window_size = self.window_size // self.spatial_merge_size // self.patch_size + grid_thw_list = grid_thw.tolist() + + for grid_t, grid_h, grid_w in grid_thw_list: + llm_grid_h, llm_grid_w = ( + grid_h // self.spatial_merge_size, + grid_w // self.spatial_merge_size, + ) + index = torch.arange(grid_t * llm_grid_h * llm_grid_w).reshape(grid_t, llm_grid_h, llm_grid_w) + pad_h = vit_merger_window_size - llm_grid_h % vit_merger_window_size + pad_w = vit_merger_window_size - llm_grid_w % vit_merger_window_size + num_windows_h = (llm_grid_h + pad_h) // vit_merger_window_size + num_windows_w = (llm_grid_w + pad_w) // vit_merger_window_size + index_padded = F.pad(index, (0, pad_w, 0, pad_h), "constant", -100) + index_padded = index_padded.reshape( + grid_t, + num_windows_h, + vit_merger_window_size, + num_windows_w, + vit_merger_window_size, + ) + index_padded = index_padded.permute(0, 1, 3, 2, 4).reshape( + grid_t, + num_windows_h * num_windows_w, + vit_merger_window_size, + vit_merger_window_size, + ) + seqlens = (index_padded != -100).sum([2, 3]).reshape(-1) + index_padded = index_padded.reshape(-1) + index_new = index_padded[index_padded != -100] + window_index.append(index_new + window_index_id) + cu_seqlens_tmp = seqlens.cumsum(0) * self.spatial_merge_unit + cu_window_seqlens[-1] + cu_window_seqlens.extend(cu_seqlens_tmp.tolist()) + window_index_id += grid_t * llm_grid_h * llm_grid_w + window_index = torch.cat(window_index, dim=0) + + return window_index, cu_window_seqlens + + @merge_with_config_defaults + @capture_outputs + def forward( + self, hidden_states: torch.Tensor, grid_thw: torch.Tensor, **kwargs: Unpack[TransformersKwargs] + ) -> tuple | BaseModelOutputWithPooling: + """ + Args: + hidden_states (`torch.Tensor` of shape `(seq_len, hidden_size)`): + The final hidden states of the model. + grid_thw (`torch.Tensor` of shape `(num_images_or_videos, 3)`): + The temporal, height and width of feature shape of each image in LLM. + + Returns: + `torch.Tensor`: hidden_states. + """ + hidden_states = self.patch_embed(hidden_states) + rotary_pos_emb = self.rot_pos_emb(grid_thw) + + window_index, cu_window_seqlens = self.get_window_index(grid_thw) + cu_window_seqlens = torch.tensor( + cu_window_seqlens, + device=hidden_states.device, + dtype=grid_thw.dtype if torch.jit.is_tracing() else torch.int32, + ) + cu_window_seqlens = torch.unique_consecutive(cu_window_seqlens) + + seq_len, _ = hidden_states.size() + hidden_states = hidden_states.reshape(seq_len // self.spatial_merge_unit, self.spatial_merge_unit, -1) + hidden_states = hidden_states[window_index, :, :] + hidden_states = hidden_states.reshape(seq_len, -1) + rotary_pos_emb = rotary_pos_emb.reshape(seq_len // self.spatial_merge_unit, self.spatial_merge_unit, -1) + rotary_pos_emb = rotary_pos_emb[window_index, :, :] + rotary_pos_emb = rotary_pos_emb.reshape(seq_len, -1) + + cu_seqlens = torch.repeat_interleave(grid_thw[:, 1] * grid_thw[:, 2], grid_thw[:, 0]).cumsum( + dim=0, + # Select dtype based on the following factors: + # - FA2 requires that cu_seqlens_q must have dtype int32 + # - torch.onnx.export requires that cu_seqlens_q must have same dtype as grid_thw + # See https://github.com/huggingface/transformers/pull/34852 for more information + dtype=grid_thw.dtype if torch.jit.is_tracing() else torch.int32, + ) + cu_seqlens = F.pad(cu_seqlens, (1, 0), value=0) + + # Modification here + for layer_num, blk in enumerate(self.blocks): + if layer_num in self.fullatt_block_indexes: + cu_seqlens_now = cu_seqlens + else: + cu_seqlens_now = cu_window_seqlens + + hidden_states = blk( + hidden_states, + cu_seqlens=cu_seqlens_now, + rotary_pos_emb=rotary_pos_emb, + **kwargs, + ) + + merged_hidden_states = self.merger(hidden_states) + reverse_indices = torch.argsort(window_index) + merged_hidden_states = merged_hidden_states[reverse_indices, :] + + return BaseModelOutputWithPooling( + last_hidden_state=hidden_states, + pooler_output=merged_hidden_states, + ) + + +class Qwen2_5OmniRotaryEmbedding(nn.Module): + inv_freq: torch.Tensor # fix linting for `register_buffer` + + def __init__(self, config: Qwen2_5OmniThinkerConfig, device=None): + super().__init__() + self.max_seq_len_cached = config.max_position_embeddings + self.original_max_seq_len = config.max_position_embeddings + + self.config = config + + self.rope_type = self.config.rope_parameters["rope_type"] + rope_init_fn: Callable = self.compute_default_rope_parameters + if self.rope_type != "default": + rope_init_fn = ROPE_INIT_FUNCTIONS[self.rope_type] + inv_freq, self.attention_scaling = rope_init_fn(self.config, device) + + self.register_buffer("inv_freq", inv_freq, persistent=False) + self.register_buffer("original_inv_freq", inv_freq.clone(), persistent=False) + + @staticmethod + def compute_default_rope_parameters( + config: Qwen2_5OmniConfig | None = None, + device: Optional["torch.device"] = None, + seq_len: int | None = None, + ) -> tuple["torch.Tensor", float]: + """ + Computes the inverse frequencies according to the original RoPE implementation + Args: + config ([`~transformers.PreTrainedConfig`]): + The model configuration. + device (`torch.device`): + The device to use for initialization of the inverse frequencies. + seq_len (`int`, *optional*): + The current sequence length. Unused for this type of RoPE. + Returns: + Tuple of (`torch.Tensor`, `float`), containing the inverse frequencies for the RoPE embeddings and the + post-processing scaling factor applied to the computed cos/sin (unused in this type of RoPE). + """ + base = config.rope_parameters["rope_theta"] + dim = getattr(config, "head_dim", None) or config.hidden_size // config.num_attention_heads + + attention_factor = 1.0 # Unused in this type of RoPE + + # Compute the inverse frequencies + inv_freq = 1.0 / ( + base ** (torch.arange(0, dim, 2, dtype=torch.int64).to(device=device, dtype=torch.float) / dim) + ) + return inv_freq, attention_factor + + # Ignore copy + def forward(self, x, position_ids): + # In contrast to other models, Qwen2_5Omni has different position ids for the grids + # So we expand the inv_freq to shape (3, ...) + inv_freq_expanded = self.inv_freq[None, None, :, None].float().expand(3, position_ids.shape[1], -1, 1) + position_ids_expanded = position_ids[:, :, None, :].float() # shape (3, bs, 1, positions) + + device_type = x.device.type if isinstance(x.device.type, str) and x.device.type != "mps" else "cpu" + with maybe_autocast(device_type=device_type, enabled=False): # Force float32 + freqs = (inv_freq_expanded.float() @ position_ids_expanded.float()).transpose(2, 3) + emb = torch.cat((freqs, freqs), dim=-1) + cos = emb.cos() * self.attention_scaling + sin = emb.sin() * self.attention_scaling + + return cos.to(dtype=x.dtype), sin.to(dtype=x.dtype) + + +def apply_multimodal_rotary_pos_emb(q, k, cos, sin, mrope_section, unsqueeze_dim=1): + """Applies Rotary Position Embedding with Multimodal Sections to the query and key tensors (https://qwenlm.github.io/blog/qwen2-vl/). + + Explanation: + Multimodal 3D rotary position embedding is an extension to 1D rotary position embedding. The input embedding + sequence contains vision (images / videos) embedding and text embedding or just contains text embedding. For + vision embedding part, we apply rotary position embedding on temporal, height and width dimension separately. + Here we split the channel dimension to 3 chunks for the temporal, height and width rotary position embedding. + For text embedding part, we just apply 1D rotary position embedding. The three rotary position index (temporal, + height and width) of text embedding is always the same, so the text embedding rotary position embedding has no + difference with modern LLMs. + + Args: + q (`torch.Tensor`): The query tensor. + k (`torch.Tensor`): The key tensor. + cos (`torch.Tensor`): The cosine part of the rotary embedding. + sin (`torch.Tensor`): The sine part of the rotary embedding. + position_ids (`torch.Tensor`): + The position indices of the tokens corresponding to the query and key tensors. For example, this can be + used to pass offsetted position ids when working with a KV-cache. + mrope_section(`List(int)`): + Multimodal rope section is for channel dimension of temporal, height and width in rope calculation. + unsqueeze_dim (`int`, *optional*, defaults to 1): + The 'unsqueeze_dim' argument specifies the dimension along which to unsqueeze cos[position_ids] and + sin[position_ids] so that they can be properly broadcasted to the dimensions of q and k. For example, note + that cos[position_ids] and sin[position_ids] have the shape [batch_size, seq_len, head_dim]. Then, if q and + k have the shape [batch_size, heads, seq_len, head_dim], then setting unsqueeze_dim=1 makes + cos[position_ids] and sin[position_ids] broadcastable to the shapes of q and k. Similarly, if q and k have + the shape [batch_size, seq_len, heads, head_dim], then set unsqueeze_dim=2. + Returns: + `tuple(torch.Tensor)` comprising of the query and key tensors rotated using the Rotary Position Embedding. + """ + mrope_section = mrope_section * 2 + cos = torch.cat([m[i % 3] for i, m in enumerate(cos.split(mrope_section, dim=-1))], dim=-1).unsqueeze( + unsqueeze_dim + ) + sin = torch.cat([m[i % 3] for i, m in enumerate(sin.split(mrope_section, dim=-1))], dim=-1).unsqueeze( + unsqueeze_dim + ) + + q_embed = (q * cos) + (rotate_half(q) * sin) + k_embed = (k * cos) + (rotate_half(k) * sin) + return q_embed, k_embed + + +class Qwen2_5OmniAttention(nn.Module): + """ + Multi-headed attention from 'Attention Is All You Need' paper. Modified to use sliding window attention: Longformer + and "Generating Long Sequences with Sparse Transformers". + """ + + def __init__(self, config: Qwen2_5OmniConfig, layer_idx: int | None = None): + super().__init__() + self.config = config + self.layer_idx = layer_idx + if layer_idx is None: + logger.warning_once( + f"Instantiating {self.__class__.__name__} without passing `layer_idx` is not recommended and will " + "to errors during the forward call, if caching is used. Please make sure to provide a `layer_idx` " + "when creating this class." + ) + + self.hidden_size = config.hidden_size + self.num_heads = config.num_attention_heads + self.head_dim = getattr(config, "head_dim", self.hidden_size // self.num_heads) + self.num_key_value_heads = config.num_key_value_heads + self.num_key_value_groups = self.num_heads // self.num_key_value_heads + self.is_causal = True + self.attention_dropout = config.attention_dropout + self.rope_parameters = config.rope_parameters + self.scaling = self.head_dim**-0.5 + + self.q_proj = nn.Linear(self.hidden_size, self.num_heads * self.head_dim, bias=True) + self.k_proj = nn.Linear(self.hidden_size, self.num_key_value_heads * self.head_dim, bias=True) + self.v_proj = nn.Linear(self.hidden_size, self.num_key_value_heads * self.head_dim, bias=True) + self.o_proj = nn.Linear(self.num_heads * self.head_dim, self.hidden_size, bias=False) + self.layer_type = config.layer_types[layer_idx] if hasattr(config, "layer_types") else None + self.sliding_window = config.sliding_window if self.layer_type == "sliding_attention" else None + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.Tensor | None = None, + position_ids: torch.LongTensor | None = None, + past_key_values: Cache | None = None, + output_attentions: bool = False, + use_cache: bool = False, + cache_position: torch.LongTensor | None = None, + position_embeddings: tuple[torch.Tensor, torch.Tensor] | None = None, + **kwargs: Unpack[FlashAttentionKwargs], + ) -> tuple[torch.Tensor, torch.Tensor | None, tuple[torch.Tensor] | None]: + bsz, q_len, _ = hidden_states.size() + + query_states = self.q_proj(hidden_states) + key_states = self.k_proj(hidden_states) + value_states = self.v_proj(hidden_states) + + query_states = query_states.view(bsz, q_len, -1, self.head_dim).transpose(1, 2) + key_states = key_states.view(bsz, q_len, -1, self.head_dim).transpose(1, 2) + value_states = value_states.view(bsz, q_len, -1, self.head_dim).transpose(1, 2) + + cos, sin = position_embeddings + query_states, key_states = apply_multimodal_rotary_pos_emb( + query_states, key_states, cos, sin, self.config.rope_parameters["mrope_section"] + ) + + if past_key_values is not None: + cache_kwargs = {"sin": sin, "cos": cos, "cache_position": cache_position} # Specific to RoPE models + key_states, value_states = past_key_values.update(key_states, value_states, self.layer_idx, cache_kwargs) + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, eager_attention_forward + ) + + attn_output, attn_weights = attention_interface( + self, + query_states, + key_states, + value_states, + attention_mask, + dropout=0.0 if not self.training else self.attention_dropout, + scaling=self.scaling, + sliding_window=self.sliding_window, + position_ids=position_ids, # pass positions for FA2 + **kwargs, + ) + + attn_output = attn_output.reshape(bsz, q_len, -1).contiguous() + attn_output = self.o_proj(attn_output) + return attn_output, attn_weights + + +class Qwen2MLP(nn.Module): + def __init__(self, config, bias: bool = False): + super().__init__() + self.hidden_size = config.hidden_size + self.intermediate_size = config.intermediate_size + self.gate_proj = nn.Linear(self.hidden_size, self.intermediate_size, bias=bias) + self.up_proj = nn.Linear(self.hidden_size, self.intermediate_size, bias=bias) + self.down_proj = nn.Linear(self.intermediate_size, self.hidden_size, bias=bias) + self.act_fn = ACT2FN[config.hidden_act] + + def forward(self, hidden_state): + return self.down_proj(self.act_fn(self.gate_proj(hidden_state)) * self.up_proj(hidden_state)) + + +class Qwen2_5OmniDecoderLayer(GradientCheckpointingLayer): + def __init__(self, config: Qwen2_5OmniTextConfig, layer_idx: int): + super().__init__() + self.hidden_size = config.hidden_size + + if config.use_sliding_window and not is_flash_attention_requested(config): + logger.warning_once( + f"Sliding Window Attention is enabled but not implemented for `{config._attn_implementation}`; " + "unexpected results may be encountered." + ) + self.self_attn = Qwen2_5OmniAttention(config, layer_idx) + + self.mlp = Qwen2MLP(config) + self.input_layernorm = Qwen2_5OmniRMSNorm(config.hidden_size, eps=config.rms_norm_eps) + self.post_attention_layernorm = Qwen2_5OmniRMSNorm(config.hidden_size, eps=config.rms_norm_eps) + self.attention_type = config.layer_types[layer_idx] + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.Tensor | None = None, + position_ids: torch.LongTensor | None = None, + past_key_values: Cache | None = None, + output_attentions: bool | None = False, + use_cache: bool | None = False, + cache_position: torch.LongTensor | None = None, + position_embeddings: tuple[torch.Tensor, torch.Tensor] | None = None, + **kwargs: Unpack[FlashAttentionKwargs], + ) -> tuple[torch.FloatTensor, tuple[torch.FloatTensor, torch.FloatTensor] | None]: + """ + Args: + hidden_states (`torch.FloatTensor`): input to the layer of shape `(batch, seq_len, embed_dim)` + attention_mask (`torch.FloatTensor`, *optional*): attention mask of size + `(batch, sequence_length)` where padding elements are indicated by 0. + output_attentions (`bool`, *optional*): + Whether or not to return the attentions tensors of all attention layers. See `attentions` under + returned tensors for more detail. + use_cache (`bool`, *optional*): + If set to `True`, `past_key_values` key value states are returned and can be used to speed up decoding + (see `past_key_values`). + past_key_values (`Cache`, *optional*): cached past key and value projection states + cache_position (`torch.LongTensor` of shape `(sequence_length)`, *optional*): + Indices depicting the position of the input sequence tokens in the sequence. + position_embeddings (`tuple[torch.FloatTensor, torch.FloatTensor]`, *optional*): + Tuple containing the cosine and sine positional embeddings of shape `(batch_size, seq_len, head_dim)`, + with `head_dim` being the embedding dimension of each attention head. + kwargs (`dict`, *optional*): + Arbitrary kwargs to be ignored, used for FSDP and other methods that injects code + into the model + """ + + residual = hidden_states + + hidden_states = self.input_layernorm(hidden_states) + + # Self Attention + hidden_states, self_attn_weights = self.self_attn( + hidden_states=hidden_states, + attention_mask=attention_mask, + position_ids=position_ids, + past_key_values=past_key_values, + output_attentions=output_attentions, + use_cache=use_cache, + cache_position=cache_position, + position_embeddings=position_embeddings, + **kwargs, + ) + hidden_states = residual + hidden_states + + # Fully Connected + residual = hidden_states + hidden_states = self.post_attention_layernorm(hidden_states) + hidden_states = self.mlp(hidden_states) + hidden_states = residual + hidden_states + + outputs = (hidden_states,) + + if output_attentions: + outputs += (self_attn_weights,) + + return outputs + + +@auto_docstring +class Qwen2_5OmniThinkerTextModel(Qwen2_5OmniPreTrainedModel): + config: Qwen2_5OmniTextConfig + input_modalities = ("text",) + _no_split_modules = ["Qwen2_5OmniDecoderLayer"] + + def __init__(self, config: Qwen2_5OmniTextConfig): + super().__init__(config) + self.padding_idx = config.pad_token_id + self.vocab_size = config.vocab_size + + self.embed_tokens = nn.Embedding(config.vocab_size, config.hidden_size, self.padding_idx) + self.layers = nn.ModuleList( + [Qwen2_5OmniDecoderLayer(config, layer_idx) for layer_idx in range(config.num_hidden_layers)] + ) + self._attn_implementation = config._attn_implementation + self.norm = Qwen2_5OmniRMSNorm(config.hidden_size, eps=config.rms_norm_eps) + self.has_sliding_layers = "sliding_attention" in self.config.layer_types + self.rotary_emb = Qwen2_5OmniRotaryEmbedding(config=config) + + self.gradient_checkpointing = False + # Initialize weights and apply final processing + self.post_init() + + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.Tensor | None = None, + position_ids: torch.LongTensor | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.FloatTensor | None = None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + cache_position: torch.LongTensor | None = None, + **kwargs: Unpack[FlashAttentionKwargs], + ) -> tuple | BaseModelOutputWithPast: + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + use_cache = use_cache if use_cache is not None else self.config.use_cache + + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + if (input_ids is None) ^ (inputs_embeds is not None): + raise ValueError("You must specify exactly one of input_ids or inputs_embeds") + + if self.gradient_checkpointing and self.training: + if use_cache: + logger.warning_once( + "`use_cache=True` is incompatible with gradient checkpointing. Setting `use_cache=False`..." + ) + use_cache = False + + # torch.jit.trace() doesn't support cache objects in the output + if use_cache and past_key_values is None and not torch.jit.is_tracing(): + past_key_values = DynamicCache(config=self.config) + + if inputs_embeds is None: + inputs_embeds = self.embed_tokens(input_ids) + + if cache_position is None: + past_seen_tokens = past_key_values.get_seq_length() if past_key_values is not None else 0 + cache_position = torch.arange( + past_seen_tokens, past_seen_tokens + inputs_embeds.shape[1], device=inputs_embeds.device + ) + + # the hard coded `3` is for temporal, height and width. + if position_ids is None: + position_ids = cache_position.view(1, 1, -1).expand(3, inputs_embeds.shape[0], -1) + elif position_ids.ndim == 2: + position_ids = position_ids[None, ...].expand(3, position_ids.shape[0], -1) + + # NOTE: we need to pass text position ids for packing. Qwen2-VL uses 3D positions + # where each dim indicates visual spatial positions for temporal/height/width grids. + # There are two scenarios when FA2-like packed masking might be activated. + # 1. User specifically passed packed `position_ids` and no attention mask. + # In this case we expect the useer to create correct position ids for all 3 grids + # and prepend text-only position ids to it. The final tensor will be [4, bs, seq-len] + # 2. User runs forward with no attention mask and no position ids. In this case, position ids + # are prepared by the model (`get_rope_index`) as `[4, bs, seq-len]` tensor. Text-only positions are + # prepended by us when creating positions so that the mask is constructed correctly. NOTE: failing to pass + # text-only positions will cause incorrect mask construction, do not change `prepare_input_for_generation` + if position_ids.ndim == 3 and position_ids.shape[0] == 4: + text_position_ids = position_ids[0] + position_ids = position_ids[1:] + else: + # If inputs are not packed (usual 3D positions), do not prepare mask from position_ids + text_position_ids = None + + # It may already have been prepared by e.g. `generate` + if not isinstance(causal_mask_mapping := attention_mask, dict): + # Prepare mask arguments + mask_kwargs = { + "config": self.config, + "inputs_embeds": inputs_embeds, + "attention_mask": attention_mask, + "cache_position": cache_position, + "past_key_values": past_key_values, + "position_ids": text_position_ids, + } + # Create the masks + causal_mask_mapping = { + "full_attention": create_causal_mask(**mask_kwargs), + } + # The sliding window alternating layers are not always activated depending on the config + if self.has_sliding_layers: + causal_mask_mapping["sliding_attention"] = create_sliding_window_causal_mask(**mask_kwargs) + + hidden_states = inputs_embeds + position_embeddings = self.rotary_emb(hidden_states, position_ids) + + # decoder layers + all_hidden_states = () if output_hidden_states else None + all_self_attns = () if output_attentions else None + + for decoder_layer in self.layers: + if output_hidden_states: + all_hidden_states += (hidden_states,) + + layer_outputs = decoder_layer( + hidden_states, + attention_mask=causal_mask_mapping[decoder_layer.attention_type], + position_embeddings=position_embeddings, + position_ids=text_position_ids, + past_key_values=past_key_values, + output_attentions=output_attentions, + use_cache=use_cache, + cache_position=cache_position, + **kwargs, + ) + + hidden_states = layer_outputs[0] + + if output_attentions: + all_self_attns += (layer_outputs[1],) + + hidden_states = self.norm(hidden_states) + + # add hidden states from the last decoder layer + if output_hidden_states: + all_hidden_states += (hidden_states,) + + if not return_dict: + return tuple( + v for v in [hidden_states, past_key_values, all_hidden_states, all_self_attns] if v is not None + ) + return BaseModelOutputWithPast( + last_hidden_state=hidden_states, + past_key_values=past_key_values, + hidden_states=all_hidden_states, + attentions=all_self_attns, + ) + + +@auto_docstring( + custom_intro=""" + The Qwen2.5OmniThinker model which consists of a audio backbone and a language model. + """ +) +class Qwen2_5OmniThinkerForConditionalGeneration(Qwen2_5OmniPreTrainedModelForConditionalGeneration, GenerationMixin): + config: Qwen2_5OmniThinkerConfig + base_model_prefix = "thinker" + _tied_weights_keys = {"lm_head.weight": "model.embed_tokens.weight"} + _no_split_modules = ["Qwen2_5OmniAudioEncoder", "Qwen2_5OmniVisionEncoder"] + + def __init__(self, config: Qwen2_5OmniThinkerConfig): + super().__init__(config) + self.audio_tower = Qwen2_5OmniAudioEncoder._from_config(config.audio_config) + self.visual = Qwen2_5OmniVisionEncoder._from_config(config.vision_config) + self.vocab_size = config.text_config.vocab_size + self.model = Qwen2_5OmniThinkerTextModel._from_config(config.text_config) + self.lm_head = nn.Linear(config.text_config.hidden_size, config.text_config.vocab_size, bias=False) + self.spatial_merge_size = config.vision_config.spatial_merge_size + self.rope_deltas = None + self.post_init() + + def get_input_embeddings(self): + return self.model.get_input_embeddings() + + def set_input_embeddings(self, value): + self.model.set_input_embeddings(value) + + @can_return_tuple + @auto_docstring + def get_video_features( + self, + pixel_values_videos: torch.FloatTensor, + video_grid_thw: torch.LongTensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple | BaseModelOutputWithPooling: + r""" + pixel_values_videos (`torch.FloatTensor` of shape `(batch_size, num_channels, image_size, image_size)`): + The tensors corresponding to the input videos. + video_grid_thw (`torch.LongTensor` of shape `(num_videos, 3)`, *optional*): + The temporal, height and width of feature shape of each video in LLM. + """ + pixel_values_videos = pixel_values_videos.type(self.visual.dtype) + return self.visual(pixel_values_videos, grid_thw=video_grid_thw, **kwargs) + + @can_return_tuple + @auto_docstring + def get_image_features( + self, + pixel_values: torch.FloatTensor, + image_grid_thw: torch.LongTensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple | BaseModelOutputWithPooling: + r""" + pixel_values (`torch.FloatTensor` of shape `(batch_size, num_channels, image_size, image_size)`): + The tensors corresponding to the input images. + image_grid_thw (`torch.LongTensor` of shape `(num_images, 3)`, *optional*): + The temporal, height and width of feature shape of each image in LLM. + """ + pixel_values = pixel_values.type(self.visual.dtype) + return self.visual(pixel_values, grid_thw=image_grid_thw, **kwargs) + + @can_return_tuple + @auto_docstring + def get_audio_features( + self, + input_features: torch.FloatTensor, + feature_attention_mask: torch.LongTensor | None = None, + audio_feature_lengths: torch.LongTensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple | BaseModelOutputWithPooling: + r""" + input_features (`torch.FloatTensor`): + The tensors corresponding to the input audios. + feature_attention_mask (`torch.LongTensor`, *optional*): + Mask to avoid performing attention on padding feature indices. Mask values selected in `[0, 1]`: + audio_feature_lengths (`torch.LongTensor` of shape `(num_audios)`, *optional*): + The length of feature shape of each audio in LLM. + """ + if feature_attention_mask is not None: + audio_feature_lengths = torch.sum(feature_attention_mask, dim=1) + input_features = input_features.permute(0, 2, 1)[feature_attention_mask.bool()].permute(1, 0) + else: + audio_feature_lengths = None + + audio_feat_lengths, audio_output_lengths = self.audio_tower._get_feat_extract_output_lengths( + audio_feature_lengths if audio_feature_lengths is not None else feature_attention_mask.sum(-1) + ) + feature_lens = audio_feature_lengths if audio_feature_lengths is not None else feature_attention_mask.sum(-1) + audio_outputs = self.audio_tower( + input_features, + feature_lens=feature_lens, + aftercnn_lens=audio_feat_lengths, + return_dict=True, + **kwargs, + ) + if audio_outputs.last_hidden_state.shape[0] != sum(audio_output_lengths.tolist()): + raise ValueError("length of audio_features should match audio_output_lengths") + + return audio_outputs + + def get_placeholder_mask( + self, + input_ids: torch.LongTensor, + inputs_embeds: torch.FloatTensor, + image_features: torch.FloatTensor | None = None, + video_features: torch.FloatTensor | None = None, + ): + """ + Obtains multimodal placeholder mask from `input_ids` or `inputs_embeds`, and checks that the placeholder token count is + equal to the length of multimodal features. If the lengths are different, an error is raised. + """ + if input_ids is None: + special_image_mask = inputs_embeds == self.get_input_embeddings()( + torch.tensor(self.config.image_token_id, dtype=torch.long, device=inputs_embeds.device) + ) + special_image_mask = special_image_mask.all(-1) + special_video_mask = inputs_embeds == self.get_input_embeddings()( + torch.tensor(self.config.video_token_id, dtype=torch.long, device=inputs_embeds.device) + ) + special_video_mask = special_video_mask.all(-1) + special_audio_mask = ( + inputs_embeds + == self.get_input_embeddings()( + torch.tensor(self.config.audio_token_id, dtype=torch.long, device=inputs_embeds.device) + ) + ).all(-1) + else: + special_image_mask = input_ids == self.config.image_token_id + special_video_mask = input_ids == self.config.video_token_id + special_audio_mask = input_ids == self.config.audio_token_id + + n_image_tokens = special_image_mask.sum() + special_image_mask = special_image_mask.unsqueeze(-1).expand_as(inputs_embeds).to(inputs_embeds.device) + if image_features is not None: + torch_compilable_check( + inputs_embeds[special_image_mask].numel() == image_features.numel(), + f"Image features and image tokens do not match, tokens: {n_image_tokens}, features: {image_features.shape[0]}", + ) + + n_video_tokens = special_video_mask.sum() + special_video_mask = special_video_mask.unsqueeze(-1).expand_as(inputs_embeds).to(inputs_embeds.device) + if video_features is not None: + torch_compilable_check( + inputs_embeds[special_video_mask].numel() == video_features.numel(), + f"Video features and video tokens do not match, tokens: {n_video_tokens}, features: {video_features.shape[0]}", + ) + + special_audio_mask = special_audio_mask.unsqueeze(-1).expand_as(inputs_embeds).to(inputs_embeds.device) + return special_image_mask, special_video_mask, special_audio_mask + + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + input_features: torch.FloatTensor | None = None, + pixel_values: torch.FloatTensor | None = None, + pixel_values_videos: torch.FloatTensor | None = None, + image_grid_thw: torch.LongTensor | None = None, + video_grid_thw: torch.LongTensor | None = None, + attention_mask: torch.Tensor | None = None, + feature_attention_mask: torch.Tensor | None = None, + audio_feature_lengths: torch.LongTensor | None = None, + position_ids: torch.LongTensor | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.FloatTensor | None = None, + rope_deltas: torch.LongTensor | None = None, + labels: torch.LongTensor | None = None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + use_audio_in_video: bool | None = None, + cache_position: torch.LongTensor | None = None, + video_second_per_grid: torch.LongTensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple | Qwen2_5OmniThinkerCausalLMOutputWithPast: + r""" + image_grid_thw (`torch.LongTensor` of shape `(num_images, 3)`, *optional*): + The temporal, height and width of feature shape of each image in LLM. + video_grid_thw (`torch.LongTensor` of shape `(num_videos, 3)`, *optional*): + The temporal, height and width of feature shape of each video in LLM. + feature_attention_mask (`torch.Tensor` of shape `(batch_size, feature_sequence_length)`, *optional*): + Mask to avoid performing attention on padding feature indices. Mask values selected in `[0, 1]`: + + - 1 for tokens that are **not masked**, + - 0 for tokens that are **masked**. + audio_feature_lengths (`torch.LongTensor` of shape `(num_audios)`, *optional*): + The length of feature shape of each audio in LLM. + rope_deltas (`torch.LongTensor` of shape `(batch_size, )`, *optional*): + The rope index difference between sequence length and multimodal rope. + labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Labels for computing the masked language modeling loss. Indices should either be in `[0, ..., + config.vocab_size]` or -100 (see `input_ids` docstring). Tokens with indices set to `-100` are ignored + (masked), the loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]`. + use_audio_in_video (`bool`, *optional*): + Whether or not use audio track in video, should same as the parameter in `process_audio_info`. + video_second_per_grid (`torch.LongTensor` of shape `(num_videos)`, *optional*): + Number of seconds per grid for each video, used for temporal feature mapping. + + Example: + + ```python + >>> from io import BytesIO + >>> from urllib.request import urlopen + >>> import librosa + >>> from qwen_vl_utils import process_vision_info + >>> from transformers import Qwen2_5OmniProcessor, Qwen2_5OmniThinkerForConditionalGeneration + + >>> thinker = Qwen2_5OmniThinkerForConditionalGeneration.from_pretrained("Qwen/Qwen2.5-Omni-7B") + >>> processor = Qwen2_5OmniProcessor.from_pretrained("Qwen/Qwen2.5-Omni-7B") + + >>> conversations = [ + >>> {'role': 'system', 'content': 'You are a helpful voice chat bot, and please respond to me in a casual conversation manner using random voice.'}, + >>> {"role": "user", "content": [ + >>> {"type": "image", "image_url": "https://www.ilankelman.org/stopsigns/australia.jpg"}, + >>> {"type": "audio", "audio_url": "https://qianwen-res.oss-cn-beijing.aliyuncs.com/Qwen2-Audio/audio/glass-breaking-151256.mp3"}, + >>> ]}, + >>> ] + + >>> text = processor.apply_chat_template(conversation, add_generation_prompt=True, tokenize=False) + >>> audios = [ librosa.load(BytesIO(urlopen( conversations[1]['content'][1]['audio_url'] ).read()), sr=self.processor.feature_extractor.sampling_rate) ] + >>> images, videos = process_vision_info(conversations) + >>> inputs = processor(text=text, audio=audios, images=images, videos=videos, return_tensors="pt", padding=True) + + >>> # Generate + >>> inputs['use_audio_in_video'] = `True` or `False` + >>> generation = thinker.generate(**inputs, max_new_tokens=2048) + >>> generate_ids = generation[:, inputs.input_ids.size(1):] + + >>> response = processor.batch_decode(generate_ids, skip_special_tokens=True, clean_up_tokenization_spaces=False)[0] + ```""" + + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + if inputs_embeds is None: + # 1. Extract the input embeddings + inputs_embeds = self.get_input_embeddings()(input_ids) + + # 2. Merge text , audios , image and video + if input_features is not None: + audio_features = self.get_audio_features( + input_features, + feature_attention_mask=feature_attention_mask, + audio_feature_lengths=audio_feature_lengths, + return_dict=True, + ).last_hidden_state + audio_features = audio_features.to(inputs_embeds.device, inputs_embeds.dtype) + _, _, audio_mask = self.get_placeholder_mask(input_ids, inputs_embeds=inputs_embeds) + inputs_embeds = inputs_embeds.masked_scatter(audio_mask, audio_features) + + if pixel_values is not None: + image_embeds = self.get_image_features(pixel_values, image_grid_thw, return_dict=True).pooler_output + image_embeds = image_embeds.to(inputs_embeds.device, inputs_embeds.dtype) + image_mask, _, _ = self.get_placeholder_mask( + input_ids, inputs_embeds=inputs_embeds, image_features=image_embeds + ) + inputs_embeds = inputs_embeds.masked_scatter(image_mask, image_embeds) + + if pixel_values_videos is not None: + video_embeds = self.get_video_features(pixel_values_videos, video_grid_thw, return_dict=True).pooler_output + video_embeds = video_embeds.to(inputs_embeds.device, inputs_embeds.dtype) + _, video_mask, _ = self.get_placeholder_mask( + input_ids, inputs_embeds=inputs_embeds, video_features=video_embeds + ) + inputs_embeds = inputs_embeds.masked_scatter(video_mask, video_embeds) + + if feature_attention_mask is not None: + audio_feature_lengths = torch.sum(feature_attention_mask, dim=1) + else: + audio_feature_lengths = None + + if attention_mask is not None and position_ids is None: + past_key_values_length = 0 if past_key_values is None else past_key_values.get_seq_length() + if past_key_values_length == 0 or self.rope_deltas is None: + delta0 = (1 - attention_mask).sum(dim=-1).unsqueeze(1) + position_ids, rope_deltas = self.get_rope_index( + input_ids, + image_grid_thw, + video_grid_thw, + attention_mask, + use_audio_in_video, + audio_feature_lengths, + video_second_per_grid, + ) + rope_deltas = rope_deltas - delta0 + self.rope_deltas = rope_deltas + else: + batch_size, seq_length = input_ids.shape + delta = (past_key_values_length + self.rope_deltas).to(input_ids.device) + position_ids = torch.arange(seq_length, device=input_ids.device) + position_ids = position_ids.view(1, -1).expand(batch_size, -1) + position_ids = position_ids.add(delta) + position_ids = position_ids.unsqueeze(0).expand(3, -1, -1) + + outputs = self.model( + attention_mask=attention_mask, + position_ids=position_ids, + past_key_values=past_key_values, + inputs_embeds=inputs_embeds, + use_cache=use_cache, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + cache_position=cache_position, + **kwargs, + ) + + hidden_states = outputs[0] + logits = self.lm_head(hidden_states) + + loss = None + if labels is not None: + loss = self.loss_function( + logits=logits, labels=labels, vocab_size=self.config.get_text_config().vocab_size + ) + + if not return_dict: + output = (logits,) + outputs + return (loss,) + output if loss is not None else output + + return Qwen2_5OmniThinkerCausalLMOutputWithPast( + loss=loss, + logits=logits, + past_key_values=outputs.past_key_values, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + rope_deltas=self.rope_deltas, + ) + + def prepare_inputs_for_generation( + self, + input_ids, + past_key_values=None, + attention_mask=None, + inputs_embeds=None, + cache_position=None, + position_ids=None, + use_cache=True, + pixel_values=None, + pixel_values_videos=None, + image_grid_thw=None, + video_grid_thw=None, + input_features=None, + feature_attention_mask=None, + use_audio_in_video=False, + video_second_per_grid=None, + is_first_iteration=False, + **kwargs, + ): + model_inputs = super().prepare_inputs_for_generation( + input_ids, + past_key_values=past_key_values, + attention_mask=attention_mask, + inputs_embeds=inputs_embeds, + cache_position=cache_position, + position_ids=position_ids, + use_cache=use_cache, + pixel_values=pixel_values, + pixel_values_videos=pixel_values_videos, + image_grid_thw=image_grid_thw, + video_grid_thw=video_grid_thw, + input_features=input_features, + feature_attention_mask=feature_attention_mask, + use_audio_in_video=use_audio_in_video, + video_second_per_grid=video_second_per_grid, + is_first_iteration=is_first_iteration, + **kwargs, + ) + + model_inputs["position_ids"] = None + + if not is_first_iteration and use_cache: + model_inputs["pixel_values"] = None + model_inputs["pixel_values_videos"] = None + model_inputs["input_features"] = None + + return model_inputs + + +############################ +# Start Talker # +############################ + + +@dataclass +@auto_docstring( + custom_intro=""" + Base class for Qwen2.5OmniTalker causal language model (or autoregressive) outputs. + """ +) +class Qwen2_5OmniTalkerCausalLMOutputWithPast(ModelOutput): + r""" + loss (`torch.FloatTensor` of shape `(1,)`, *optional*, returned when `labels` is provided): + Language modeling loss (for next-token prediction). + logits (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.vocab_size)`): + Prediction scores of the language modeling head (scores for each vocabulary token before SoftMax). + past_key_values (`Cache`, *optional*, returned when `use_cache=True` is passed or when `config.use_cache=True`): + It is a [`~cache_utils.Cache`] instance. For more details, see our [kv cache guide](https://huggingface.co/docs/transformers/en/kv_cache). + + Contains pre-computed hidden-states (key and values in the self-attention blocks) that can be used (see + `past_key_values` input) to speed up sequential decoding. + rope_deltas (`torch.LongTensor` of shape `(batch_size, )`, *optional*): + The rope index difference between sequence length and multimodal rope. + thinker_reply_part (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`): + Hidden states from the thinker model that are used as input for the talker model. These represent the encoded + response that the talker model will use to generate speech tokens. + """ + + loss: torch.FloatTensor | None = None + logits: torch.FloatTensor | None = None + past_key_values: Cache | None = None + hidden_states: tuple[torch.FloatTensor] | None = None + attentions: tuple[torch.FloatTensor] | None = None + rope_deltas: torch.LongTensor | None = None + thinker_reply_part: torch.FloatTensor | None = None + + +@auto_docstring +class Qwen2_5OmniTalkerModel(Qwen2_5OmniPreTrainedModel): + config: Qwen2_5OmniTalkerConfig + input_modalities = ("image", "video", "audio", "text") + + _no_split_modules = ["Qwen2_5OmniTalkerDecoderLayer"] + + def __init__(self, config: Qwen2_5OmniTalkerConfig): + super().__init__(config) + self.padding_idx = config.pad_token_id + self.vocab_size = config.vocab_size + self.embed_tokens = nn.Embedding(config.vocab_size, config.embedding_size, self.padding_idx) + self.layers = nn.ModuleList( + [Qwen2_5OmniDecoderLayer(config, layer_idx) for layer_idx in range(config.num_hidden_layers)] + ) + self._attn_implementation = config._attn_implementation + self.norm = Qwen2_5OmniRMSNorm(config.hidden_size, eps=config.rms_norm_eps) + self.has_sliding_layers = "sliding_attention" in self.config.layer_types + self.rotary_emb = Qwen2_5OmniRotaryEmbedding(config=config) + + self.gradient_checkpointing = False + # Initialize weights and apply final processing + self.post_init() + + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.Tensor | None = None, + position_ids: torch.LongTensor | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.FloatTensor | None = None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + cache_position: torch.LongTensor | None = None, + **kwargs: Unpack[FlashAttentionKwargs], + ) -> tuple | BaseModelOutputWithPast: + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + use_cache = use_cache if use_cache is not None else self.config.use_cache + + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + if (input_ids is None) ^ (inputs_embeds is not None): + raise ValueError("You must specify exactly one of input_ids or inputs_embeds") + + if self.gradient_checkpointing and self.training: + if use_cache: + logger.warning_once( + "`use_cache=True` is incompatible with gradient checkpointing. Setting `use_cache=False`..." + ) + use_cache = False + + # torch.jit.trace() doesn't support cache objects in the output + if use_cache and past_key_values is None and not torch.jit.is_tracing(): + past_key_values = DynamicCache(config=self.config) + + if inputs_embeds is None: + inputs_embeds = self.embed_tokens(input_ids) + + if cache_position is None: + past_seen_tokens = past_key_values.get_seq_length() if past_key_values is not None else 0 + cache_position = torch.arange( + past_seen_tokens, past_seen_tokens + inputs_embeds.shape[1], device=inputs_embeds.device + ) + + # the hard coded `3` is for temporal, height and width. + if position_ids is None: + position_ids = cache_position.view(1, 1, -1).expand(3, inputs_embeds.shape[0], -1) + elif position_ids.ndim == 2: + position_ids = position_ids[None, ...].expand(3, position_ids.shape[0], -1) + + # NOTE: we need to pass text position ids for packing. Qwen2-VL uses 3D positions + # where each dim indicates visual spatial positions for temporal/height/width grids. + # There are two scenarios when FA2-like packed masking might be activated. + # 1. User specifically passed packed `position_ids` and no attention mask. + # In this case we expect the useer to create correct position ids for all 3 grids + # and prepend text-only position ids to it. The final tensor will be [4, bs, seq-len] + # 2. User runs forward with no attention mask and no position ids. In this case, position ids + # are prepared by the model (`get_rope_index`) as `[4, bs, seq-len]` tensor. Text-only positions are + # prepended by us when creating positions so that the mask is constructed correctly. NOTE: failing to pass + # text-only positions will cause incorrect mask construction, do not change `prepare_input_for_generation` + if position_ids.ndim == 3 and position_ids.shape[0] == 4: + text_position_ids = position_ids[0] + position_ids = position_ids[1:] + else: + # If inputs are not packed (usual 3D positions), do not prepare mask from position_ids + text_position_ids = None + + # It may already have been prepared by e.g. `generate` + if not isinstance(causal_mask_mapping := attention_mask, dict): + # Prepare mask arguments + mask_kwargs = { + "config": self.config, + "inputs_embeds": inputs_embeds, + "attention_mask": attention_mask, + "cache_position": cache_position, + "past_key_values": past_key_values, + "position_ids": text_position_ids, + } + # Create the masks + causal_mask_mapping = { + "full_attention": create_causal_mask(**mask_kwargs), + } + # The sliding window alternating layers are not always activated depending on the config + if self.has_sliding_layers: + causal_mask_mapping["sliding_attention"] = create_sliding_window_causal_mask(**mask_kwargs) + + hidden_states = inputs_embeds + position_embeddings = self.rotary_emb(hidden_states, position_ids) + + # decoder layers + all_hidden_states = () if output_hidden_states else None + all_self_attns = () if output_attentions else None + + for decoder_layer in self.layers: + if output_hidden_states: + all_hidden_states += (hidden_states,) + + layer_outputs = decoder_layer( + hidden_states, + attention_mask=causal_mask_mapping[decoder_layer.attention_type], + position_embeddings=position_embeddings, + position_ids=text_position_ids, + past_key_values=past_key_values, + output_attentions=output_attentions, + use_cache=use_cache, + cache_position=cache_position, + **kwargs, + ) + + hidden_states = layer_outputs[0] + + if output_attentions: + all_self_attns += (layer_outputs[1],) + + hidden_states = self.norm(hidden_states) + + # add hidden states from the last decoder layer + if output_hidden_states: + all_hidden_states += (hidden_states,) + + if not return_dict: + return tuple( + v for v in [hidden_states, past_key_values, all_hidden_states, all_self_attns] if v is not None + ) + return BaseModelOutputWithPast( + last_hidden_state=hidden_states, + past_key_values=past_key_values, + hidden_states=all_hidden_states, + attentions=all_self_attns, + ) + + +class Qwen2_5OmniTalkerForConditionalGeneration(Qwen2_5OmniPreTrainedModelForConditionalGeneration, GenerationMixin): + config: Qwen2_5OmniTalkerConfig + base_model_prefix = "talker" + output_modalities = ("audio",) + + def __init__(self, config: Qwen2_5OmniTalkerConfig): + super().__init__(config) + + self.thinker_to_talker_proj = nn.Linear(config.embedding_size, config.hidden_size) + + self.model = Qwen2_5OmniTalkerModel(config) + self.codebook_size = config.vocab_size + self.codec_head = nn.Linear(config.hidden_size, self.codebook_size, bias=False) + + self.codec_bos_token = config.tts_codec_start_token_id + self.codec_eos_token = config.tts_codec_end_token_id + self.codec_pad_token = config.tts_codec_pad_token_id + self.codec_mask_token = config.tts_codec_mask_token_id + + self.text_bos_token = config.tts_text_start_token_id + self.text_eos_token = config.tts_text_end_token_id + self.text_pad_token = config.tts_text_pad_token_id + + self.spatial_merge_size = self.config.spatial_merge_size + self.rope_deltas = None + + self.post_init() + + def get_input_embeddings(self): + return self.model.get_input_embeddings() + + def set_input_embeddings(self, value): + self.model.set_input_embeddings(value) + + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.Tensor | None = None, + position_ids: torch.LongTensor | None = None, + past_key_values: Cache | None = None, + thinker_reply_part: torch.FloatTensor | None = None, + inputs_embeds: torch.FloatTensor | None = None, + rope_deltas: torch.LongTensor | None = None, + use_cache: bool | None = None, + cache_position: torch.LongTensor | None = None, + input_text_ids: torch.LongTensor | None = None, + image_grid_thw: torch.LongTensor | None = None, + video_grid_thw: torch.LongTensor | None = None, + use_audio_in_video: bool | None = None, + audio_feature_lengths: torch.LongTensor | None = None, + video_second_per_grid: torch.LongTensor | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + **kwargs, + ) -> tuple | Qwen2_5OmniTalkerCausalLMOutputWithPast: + r""" + thinker_reply_part (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*): + Hidden states from the thinker model's output that represent the text reply part to be processed. + rope_deltas (`torch.LongTensor` of shape `(batch_size, )`, *optional*): + The rope index difference between sequence length and multimodal rope. + input_text_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Input token IDs for text-only content, used for position calculation in multimodal contexts. + image_grid_thw (`torch.LongTensor` of shape `(num_images, 3)`, *optional*): + The temporal, height and width of feature shape of each image in LLM. + video_grid_thw (`torch.LongTensor` of shape `(num_videos, 3)`, *optional*): + The temporal, height and width of feature shape of each video in LLM. + use_audio_in_video (`bool`, *optional*): + Whether or not use audio track in video, should same as the parameter in `process_audio_info`. + audio_feature_lengths (`torch.LongTensor` of shape `(num_audios)`, *optional*): + The length of feature shape of each audio in LLM. + video_second_per_grid (`torch.LongTensor` of shape `(num_videos)`, *optional*): + Number of seconds per grid for each video, used for temporal feature mapping. + + Example: + + ```python + >>> from io import BytesIO + >>> from urllib.request import urlopen + >>> import librosa + >>> from transformers import AutoProcessor, Qwen2_5OmniTalkerForConditionalGeneration + + >>> model = Qwen2_5OmniTalkerForConditionalGeneration.from_pretrained("Qwen/Qwen2-Audio-7B") + >>> processor = AutoProcessor.from_pretrained("Qwen/Qwen2-Audio-7B") + + >>> prompt = "<|audio_bos|><|AUDIO|><|audio_eos|>Generate the caption in English:" + >>> url = "https://qianwen-res.oss-cn-beijing.aliyuncs.com/Qwen2-Audio/audio/glass-breaking-151256.mp3" + >>> audio, _ = librosa.load(BytesIO(urlopen(url).read()), sr=self.processor.feature_extractor.sampling_rate) + + >>> inputs = processor(text=prompt, audio=audio, return_tensors="pt") + + >>> # Generate + >>> generate_ids = model.generate(**inputs, max_length=30) + >>> processor.batch_decode(generate_ids, skip_special_tokens=True, clean_up_tokenization_spaces=False)[0] + "Generate the caption in English: Glass is breaking." + ```""" + + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + if attention_mask is not None and position_ids is None: + past_key_values_length = 0 if past_key_values is None else past_key_values.get_seq_length() + if past_key_values_length == 0 or self.rope_deltas is None: + position_ids, rope_deltas = self.get_rope_index( + input_text_ids, + image_grid_thw, + video_grid_thw, + attention_mask, + use_audio_in_video, + audio_feature_lengths, + video_second_per_grid, + ) + + if inputs_embeds is not None: + inputs_embeds[:, -1, :] += self.get_input_embeddings()( + torch.tensor([self.codec_bos_token], dtype=torch.long, device=inputs_embeds.device) + ) + inputs_embeds[:, -2, :] += self.get_input_embeddings()( + torch.tensor([self.codec_pad_token], dtype=torch.long, device=inputs_embeds.device) + ) + self.rope_deltas = rope_deltas + + else: + if inputs_embeds is not None: + batch_size, seq_length, _ = inputs_embeds.shape + else: + batch_size, seq_length = input_ids.shape + + delta = (past_key_values_length + self.rope_deltas).to(input_ids.device) + position_ids = torch.arange(seq_length, device=input_ids.device) + position_ids = position_ids.view(1, -1).expand(batch_size, -1) + position_ids = position_ids.add(delta) + position_ids = position_ids.unsqueeze(0).expand(3, -1, -1) + + if inputs_embeds is None: + # 1. Inference tokens after second token + codec_embeds = self.get_input_embeddings()(input_ids) + inputs_embeds = codec_embeds + thinker_reply_part[:, :1, :] + if thinker_reply_part.shape[1] > 1: + thinker_reply_part = thinker_reply_part[:, 1:, :] + + talker_lm_input = self.thinker_to_talker_proj(inputs_embeds) + + if attention_mask is not None: + attention_mask = attention_mask.to(inputs_embeds.device) + + outputs = self.model( + attention_mask=attention_mask, + position_ids=position_ids, + past_key_values=past_key_values, + inputs_embeds=talker_lm_input, + use_cache=use_cache, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + + hidden_states = outputs[0] + logits = self.codec_head(hidden_states) + logits = logits.float() + + loss = None + + if not return_dict: + output = (logits,) + outputs[1:] + return (loss,) + output if loss is not None else output + + return Qwen2_5OmniTalkerCausalLMOutputWithPast( + loss=loss, + logits=logits, + past_key_values=outputs.past_key_values, + hidden_states=hidden_states, + attentions=outputs.attentions, + rope_deltas=self.rope_deltas, + thinker_reply_part=thinker_reply_part, + ) + + def _get_initial_cache_position(self, seq_length, device, model_kwargs): + # Talker needs to calculate cache_position with input_ids, so pop inputs_embeds temporarily + inputs_embeds = model_kwargs.pop("inputs_embeds") + model_kwargs = super()._get_initial_cache_position(seq_length, device, model_kwargs) + model_kwargs["inputs_embeds"] = inputs_embeds + return model_kwargs + + # prepare inputs for talker lm generation + def prepare_inputs_for_generation( + self, + input_ids, + input_text_ids, + past_key_values=None, + attention_mask=None, + inputs_embeds=None, + thinker_reply_part=None, + cache_position=None, + position_ids=None, + use_cache=True, + pixel_values=None, + pixel_values_videos=None, + image_grid_thw=None, + video_grid_thw=None, + input_audio_features=None, + audio_feature_attention_mask=None, + audio_feature_lengths=None, + use_audio_in_video=False, + video_second_per_grid=None, + **kwargs, + ): + model_inputs = super().prepare_inputs_for_generation( + input_ids, + past_key_values, + attention_mask, + inputs_embeds, + cache_position, + use_cache=use_cache, + thinker_reply_part=thinker_reply_part, + input_text_ids=input_text_ids, + image_grid_thw=image_grid_thw, + video_grid_thw=video_grid_thw, + use_audio_in_video=use_audio_in_video, + audio_feature_lengths=audio_feature_lengths, + video_second_per_grid=video_second_per_grid, + **kwargs, + ) + + model_inputs["position_ids"] = None + + return model_inputs + + def _update_model_kwargs_for_generation( + self, + outputs: ModelOutput, + model_kwargs: dict[str, Any], + is_encoder_decoder: bool = False, + num_new_tokens: int = 1, + ) -> dict[str, Any]: + model_kwargs = super()._update_model_kwargs_for_generation( + outputs, model_kwargs, is_encoder_decoder, num_new_tokens + ) + + if getattr(outputs, "thinker_reply_part", None) is not None: + model_kwargs["thinker_reply_part"] = outputs.thinker_reply_part + + return model_kwargs + + +class Qwen2_5OmniDiTRotaryEmbedding(nn.Module): + inv_freq: torch.Tensor # fix linting for `register_buffer` + + def __init__(self, config: Qwen2_5OmniDiTConfig, device=None): + super().__init__() + self.max_seq_len_cached = config.max_position_embeddings + self.original_max_seq_len = config.max_position_embeddings + + self.config = config + + self.rope_type = self.config.rope_parameters["rope_type"] + rope_init_fn: Callable = self.compute_default_rope_parameters + if self.rope_type != "default": + rope_init_fn = ROPE_INIT_FUNCTIONS[self.rope_type] + inv_freq, self.attention_scaling = rope_init_fn(self.config, device) + + self.register_buffer("inv_freq", inv_freq, persistent=False) + self.register_buffer("original_inv_freq", inv_freq.clone(), persistent=False) + + @staticmethod + def compute_default_rope_parameters( + config: Qwen2_5OmniDiTConfig | None = None, + device: Optional["torch.device"] = None, + seq_len: int | None = None, + ) -> tuple["torch.Tensor", float]: + """ + Computes the inverse frequencies according to the original RoPE implementation + Args: + config ([`~transformers.PreTrainedConfig`]): + The model configuration. + device (`torch.device`): + The device to use for initialization of the inverse frequencies. + seq_len (`int`, *optional*): + The current sequence length. Unused for this type of RoPE. + Returns: + Tuple of (`torch.Tensor`, `float`), containing the inverse frequencies for the RoPE embeddings and the + post-processing scaling factor applied to the computed cos/sin (unused in this type of RoPE). + """ + base = config.rope_parameters["rope_theta"] + dim = getattr(config, "head_dim", None) or config.hidden_size // config.num_attention_heads + + attention_factor = 1.0 # Unused in this type of RoPE + + # Compute the inverse frequencies + inv_freq = 1.0 / ( + base ** (torch.arange(0, dim, 2, dtype=torch.int64).to(device=device, dtype=torch.float) / dim) + ) + return inv_freq, attention_factor + + @torch.no_grad() + @dynamic_rope_update # power user: used with advanced RoPE types (e.g. dynamic rope) + def forward(self, x, position_ids): + inv_freq_expanded = self.inv_freq[None, :, None].float().expand(position_ids.shape[0], -1, 1).to(x.device) + position_ids_expanded = position_ids[:, None, :].float() + + device_type = x.device.type if isinstance(x.device.type, str) and x.device.type != "mps" else "cpu" + with maybe_autocast(device_type=device_type, enabled=False): # Force float32 + freqs = (inv_freq_expanded.float() @ position_ids_expanded.float()).transpose(1, 2) + emb = torch.cat((freqs, freqs), dim=-1) + cos = emb.cos() * self.attention_scaling + sin = emb.sin() * self.attention_scaling + + return cos.to(dtype=x.dtype), sin.to(dtype=x.dtype) + + +class TimeDelayNetBlock(nn.Module): + def __init__( + self, + in_channels, + out_channels, + kernel_size, + dilation, + ): + super().__init__() + self.conv = nn.Conv1d( + in_channels=in_channels, + out_channels=out_channels, + kernel_size=kernel_size, + dilation=dilation, + padding="same", + padding_mode="reflect", + ) + self.activation = nn.ReLU() + + def forward(self, hidden_states: torch.Tensor): + return self.activation(self.conv(hidden_states)) + + +class Res2NetBlock(torch.nn.Module): + def __init__(self, in_channels, out_channels, scale=8, kernel_size=3, dilation=1): + super().__init__() + + in_channel = in_channels // scale + hidden_channel = out_channels // scale + + self.blocks = nn.ModuleList( + [ + TimeDelayNetBlock( + in_channel, + hidden_channel, + kernel_size=kernel_size, + dilation=dilation, + ) + for i in range(scale - 1) + ] + ) + self.scale = scale + + def forward(self, hidden_states): + outputs = [] + for i, hidden_part in enumerate(torch.chunk(hidden_states, self.scale, dim=1)): + if i == 0: + output_part = hidden_part + elif i == 1: + output_part = self.blocks[i - 1](hidden_part) + else: + output_part = self.blocks[i - 1](hidden_part + output_part) + outputs.append(output_part) + output = torch.cat(outputs, dim=1) + return output + + +class SqueezeExcitationBlock(nn.Module): + def __init__(self, in_channels, se_channels, out_channels): + super().__init__() + + self.conv1 = nn.Conv1d( + in_channels=in_channels, + out_channels=se_channels, + kernel_size=1, + padding="same", + padding_mode="reflect", + ) + self.relu = nn.ReLU(inplace=True) + self.conv2 = nn.Conv1d( + in_channels=se_channels, + out_channels=out_channels, + kernel_size=1, + padding="same", + padding_mode="reflect", + ) + self.sigmoid = nn.Sigmoid() + + def forward(self, hidden_states): + hidden_states_mean = hidden_states.mean(dim=2, keepdim=True) + + hidden_states_mean = self.relu(self.conv1(hidden_states_mean)) + hidden_states_mean = self.sigmoid(self.conv2(hidden_states_mean)) + + return hidden_states * hidden_states_mean + + +class AttentiveStatisticsPooling(nn.Module): + """This class implements an attentive statistic pooling layer for each channel. + It returns the concatenated mean and std of the input tensor. + """ + + def __init__(self, channels, attention_channels=128): + super().__init__() + + self.eps = 1e-12 + self.tdnn = TimeDelayNetBlock(channels * 3, attention_channels, 1, 1) + self.tanh = nn.Tanh() + self.conv = nn.Conv1d( + in_channels=attention_channels, + out_channels=channels, + kernel_size=1, + padding="same", + padding_mode="reflect", + ) + + def _length_to_mask(self, length, max_len=None, dtype=None, device=None): + """Creates a binary mask for each sequence. + + Reference: https://discuss.pytorch.org/t/how-to-generate-variable-length-mask/23397/3 + + Arguments + --------- + length : torch.LongTensor + Containing the length of each sequence in the batch. Must be 1D. + max_len : int + Max length for the mask, also the size of the second dimension. + dtype : torch.dtype, default: None + The dtype of the generated mask. + device: torch.device, default: None + The device to put the mask variable. + + Returns + ------- + mask : tensor + The binary mask. + """ + + if max_len is None: + max_len = length.max().long().item() # using arange to generate mask + mask = torch.arange(max_len, device=length.device, dtype=length.dtype).expand( + len(length), max_len + ) < length.unsqueeze(1) + + mask = torch.as_tensor(mask, dtype=dtype, device=device) + return mask + + def _compute_statistics(self, x, m, dim=2): + mean = (m * x).sum(dim) + std = torch.sqrt((m * (x - mean.unsqueeze(dim)).pow(2)).sum(dim).clamp(self.eps)) + return mean, std + + def forward(self, hidden_states): + seq_length = hidden_states.shape[-1] + lengths = torch.ones(hidden_states.shape[0], device=hidden_states.device) + + # Make binary mask of shape [N, 1, L] + mask = self._length_to_mask( + lengths * seq_length, max_len=seq_length, dtype=hidden_states.dtype, device=hidden_states.device + ) + mask = mask.unsqueeze(1) + + # Expand the temporal context of the pooling layer by allowing the + # self-attention to look at global properties of the utterance. + total = mask.sum(dim=2, keepdim=True) + + mean, std = self._compute_statistics(hidden_states, mask / total) + mean = mean.unsqueeze(2).repeat(1, 1, seq_length) + std = std.unsqueeze(2).repeat(1, 1, seq_length) + attention = torch.cat([hidden_states, mean, std], dim=1) + + # Apply layers + attention = self.conv(self.tanh(self.tdnn(attention))) + + # Filter out zero-paddings + attention = attention.masked_fill(mask == 0, float("-inf")) + + attention = F.softmax(attention, dim=2) + mean, std = self._compute_statistics(hidden_states, attention) + # Append mean and std of the batch + pooled_stats = torch.cat((mean, std), dim=1) + pooled_stats = pooled_stats.unsqueeze(2) + + return pooled_stats + + +class SqueezeExcitationRes2NetBlock(nn.Module): + """An implementation of building block in ECAPA-TDNN, i.e., + TDNN-Res2Net-TDNN-SqueezeExcitationBlock. + """ + + def __init__( + self, + in_channels, + out_channels, + res2net_scale=8, + se_channels=128, + kernel_size=1, + dilation=1, + ): + super().__init__() + self.out_channels = out_channels + self.tdnn1 = TimeDelayNetBlock( + in_channels, + out_channels, + kernel_size=1, + dilation=1, + ) + self.res2net_block = Res2NetBlock(out_channels, out_channels, res2net_scale, kernel_size, dilation) + self.tdnn2 = TimeDelayNetBlock( + out_channels, + out_channels, + kernel_size=1, + dilation=1, + ) + self.se_block = SqueezeExcitationBlock(out_channels, se_channels, out_channels) + + def forward(self, hidden_state): + residual = hidden_state + + hidden_state = self.tdnn1(hidden_state) + hidden_state = self.res2net_block(hidden_state) + hidden_state = self.tdnn2(hidden_state) + hidden_state = self.se_block(hidden_state) + + return hidden_state + residual + + +class ECAPA_TimeDelayNet(torch.nn.Module): + """An implementation of the speaker embedding model in a paper. + "ECAPA-TDNN: Emphasized Channel Attention, Propagation and Aggregation in + TDNN Based Speaker Verification" (https://huggingface.co/papers/2005.07143). + """ + + def __init__(self, config: Qwen2_5OmniDiTConfig): + super().__init__() + if len(config.enc_channels) != len(config.enc_kernel_sizes) or len(config.enc_channels) != len( + config.enc_dilations + ): + raise ValueError("enc_channels, enc_kernel_sizes and enc_dilations should have same length") + self.channels = config.enc_channels + self.blocks = nn.ModuleList() + + # The initial TDNN layer + self.blocks.append( + TimeDelayNetBlock( + config.mel_dim, + config.enc_channels[0], + config.enc_kernel_sizes[0], + config.enc_dilations[0], + ) + ) + + # SE-Res2Net layers + for i in range(1, len(config.enc_channels) - 1): + self.blocks.append( + SqueezeExcitationRes2NetBlock( + config.enc_channels[i - 1], + config.enc_channels[i], + res2net_scale=config.enc_res2net_scale, + se_channels=config.enc_se_channels, + kernel_size=config.enc_kernel_sizes[i], + dilation=config.enc_dilations[i], + ) + ) + + # Multi-layer feature aggregation + self.mfa = TimeDelayNetBlock( + config.enc_channels[-1], + config.enc_channels[-1], + config.enc_kernel_sizes[-1], + config.enc_dilations[-1], + ) + + # Attentive Statistical Pooling + self.asp = AttentiveStatisticsPooling( + config.enc_channels[-1], + attention_channels=config.enc_attention_channels, + ) + + # Final linear transformation + self.fc = nn.Conv1d( + in_channels=config.enc_channels[-1] * 2, + out_channels=config.enc_dim, + kernel_size=1, + padding="same", + padding_mode="reflect", + ) + + def forward(self, hidden_states): + # Minimize transpose for efficiency + hidden_states = hidden_states.transpose(1, 2) + + hidden_states_list = [] + for layer in self.blocks: + hidden_states = layer(hidden_states) + hidden_states_list.append(hidden_states) + + # Multi-layer feature aggregation + hidden_states = torch.cat(hidden_states_list[1:], dim=1) + hidden_states = self.mfa(hidden_states) + + # Attentive Statistical Pooling + hidden_states = self.asp(hidden_states) + + # Final linear transformation + hidden_states = self.fc(hidden_states) + + hidden_states = hidden_states.squeeze(-1) + return hidden_states + + +class DiTInputEmbedding(nn.Module): + def __init__(self, config: Qwen2_5OmniDiTConfig): + super().__init__() + self.proj = nn.Linear( + config.mel_dim + config.enc_dim + config.enc_emb_dim + config.emb_dim, + config.hidden_size, + ) + self.spk_encoder = ECAPA_TimeDelayNet(config) + + def forward( + self, + hidden_states: torch.Tensor, + speaker_embedding: torch.Tensor, + condition_vector: torch.Tensor, + code_embed: torch.Tensor, + drop_audio_cond: bool | None = False, + code_embed_uncond: bool | None = None, + apply_cfg: bool | None = True, + ): + if apply_cfg: + hidden_states = torch.cat([hidden_states, hidden_states], dim=0) + speaker_embedding = torch.cat([speaker_embedding, torch.zeros_like(speaker_embedding)], dim=0) + condition_vector = torch.cat([condition_vector, torch.zeros_like(condition_vector)], dim=0) + code_embed = torch.cat([code_embed, code_embed_uncond], dim=0) + elif drop_audio_cond: # cfg for cond audio + condition_vector = torch.zeros_like(condition_vector) + speaker_embedding = torch.zeros_like(speaker_embedding) + condition_vector = self.spk_encoder(condition_vector).unsqueeze(1).repeat(1, hidden_states.size(1), 1) + hidden_states = self.proj(torch.cat((hidden_states, condition_vector, code_embed, speaker_embedding), dim=-1)) + + return hidden_states + + +# Transformer backbone using DiT blocks +class DiTCodecEmbedding(nn.Module): + def __init__(self, codec_num_embeds, codec_dim, repeats): + super().__init__() + self.repeats = repeats + self.codec_embed = nn.Embedding(codec_num_embeds + 1, codec_dim) + + def forward(self, code, drop_code=False): + if drop_code: + code = torch.zeros_like(code) + code_embed = self.codec_embed(code) + + code_embed = torch.repeat_interleave(code_embed, repeats=self.repeats, dim=1) + return code_embed + + +# AdaLayerNormZero +# return with modulated x for attn input, and params for later mlp modulation +class Qwen2_5_OmniAdaLayerNormZero(nn.Module): + def __init__(self, dim): + super().__init__() + + self.silu = nn.SiLU() + self.linear = nn.Linear(dim, dim * 6) + + self.norm = nn.LayerNorm(dim, elementwise_affine=False, eps=1e-6) + + def forward(self, hidden_states, emb=None): + emb = self.linear(self.silu(emb)) + shift_msa, scale_msa, gate_msa, shift_mlp, scale_mlp, gate_mlp = torch.chunk(emb, 6, dim=1) + + hidden_states = self.norm(hidden_states) * (1 + scale_msa[:, None]) + shift_msa[:, None] + return hidden_states, gate_msa, shift_mlp, scale_mlp, gate_mlp + + +# AdaLayerNormZero for final layer +# return only with modulated x for attn input, cuz no more mlp modulation +class Qwen2_5_OmniAdaLayerNormZero_Final(nn.Module): + def __init__(self, dim): + super().__init__() + + self.silu = nn.SiLU() + self.linear = nn.Linear(dim, dim * 2) + + self.norm = nn.LayerNorm(dim, elementwise_affine=False, eps=1e-6) + + def forward(self, hidden_states, emb): + emb = self.linear(self.silu(emb)) + scale, shift = torch.chunk(emb, 2, dim=1) + + hidden_states = self.norm(hidden_states) * (1 + scale)[:, None, :] + shift[:, None, :] + return hidden_states + + +# FeedForward +class DiTMLP(nn.Module): + def __init__(self, dim, mult=4, dropout=0.0): + super().__init__() + inner_dim = int(dim * mult) + + self.ff = nn.ModuleList( + [ + nn.Linear(dim, inner_dim), + nn.GELU(approximate="tanh"), + nn.Dropout(dropout), + nn.Linear(inner_dim, dim), + ] + ) + + def forward(self, hidden_states): + for layer in self.ff: + hidden_states = layer(hidden_states) + return hidden_states + + +# Modified from Llama with a different rotate function, will fixed in next release +def apply_rotary_pos_emb(q, k, cos, sin, unsqueeze_dim=1): + """Applies Rotary Position Embedding to the query and key tensors. + + Args: + q (`torch.Tensor`): The query tensor. + k (`torch.Tensor`): The key tensor. + cos (`torch.Tensor`): The cosine part of the rotary embedding. + sin (`torch.Tensor`): The sine part of the rotary embedding. + unsqueeze_dim (`int`, *optional*, defaults to 1): + The 'unsqueeze_dim' argument specifies the dimension along which to unsqueeze cos[position_ids] and + sin[position_ids] so that they can be properly broadcasted to the dimensions of q and k. For example, note + that cos[position_ids] and sin[position_ids] have the shape [batch_size, seq_len, head_dim]. Then, if q and + k have the shape [batch_size, heads, seq_len, head_dim], then setting unsqueeze_dim=1 makes + cos[position_ids] and sin[position_ids] broadcastable to the shapes of q and k. Similarly, if q and k have + the shape [batch_size, seq_len, heads, head_dim], then set unsqueeze_dim=2. + Returns: + `tuple(torch.Tensor)` comprising of the query and key tensors rotated using the Rotary Position Embedding. + """ + + def rotate_half_codec(x): + # x = rearrange(x, "... (d r) -> ... d r", r=2) + x = x.reshape(*x.shape[:-1], -1, 2) + x1, x2 = x.unbind(dim=-1) + x = torch.stack((-x2, x1), dim=-1) + return x.reshape(*x.shape[:-2], -1) + + cos = cos.unsqueeze(unsqueeze_dim) + sin = sin.unsqueeze(unsqueeze_dim) + q_embed = (q * cos) + (rotate_half_codec(q) * sin) + k_embed = (k * cos) + (rotate_half_codec(k) * sin) + return q_embed, k_embed + + +class DiTAttention(nn.Module): + def __init__(self, config: Qwen2_5OmniDiTConfig): + super().__init__() + + self.config = config + self.dim = config.hidden_size + self.heads = config.num_attention_heads + self.inner_dim = config.head_dim * config.num_attention_heads + self.dropout = config.dropout + self.is_causal = False + + self.to_q = nn.Linear(config.hidden_size, self.inner_dim) + self.to_k = nn.Linear(config.hidden_size, self.inner_dim) + self.to_v = nn.Linear(config.hidden_size, self.inner_dim) + + self.to_out = nn.ModuleList([nn.Linear(self.inner_dim, config.hidden_size), nn.Dropout(config.dropout)]) + + def forward( + self, + hidden_states, # noised input x + position_embeddings=None, # rotary position embedding for x + attention_mask=None, + ) -> torch.Tensor: + batch_size = hidden_states.shape[0] + + # `sample` projections. + query = self.to_q(hidden_states) + key = self.to_k(hidden_states) + value = self.to_v(hidden_states) + + # attention + inner_dim = key.shape[-1] + head_dim = inner_dim // self.heads + query = query.view(batch_size, -1, self.heads, head_dim).transpose(1, 2) + key = key.view(batch_size, -1, self.heads, head_dim).transpose(1, 2) + value = value.view(batch_size, -1, self.heads, head_dim).transpose(1, 2) + + # apply rotary position embedding + # Due to training process, only first head is applied with RoPE, will be fixed at next release + cos, sin = position_embeddings + query[:, :1], key[:, :1] = apply_rotary_pos_emb(query[:, :1], key[:, :1], cos, sin) + + attention_interface = ALL_ATTENTION_FUNCTIONS[self.config._attn_implementation] + attention_weights, _ = attention_interface( + self, + query, + key, + value, + attention_mask=attention_mask, + is_causal=False, + ) + + # mask. e.g. inference got a batch with different target durations, mask out the padding + attention_weights = attention_weights.reshape(batch_size, -1, self.heads * head_dim) + attention_weights = attention_weights.to(query.dtype) + + # linear proj + attention_output = self.to_out[0](attention_weights) + attention_output = self.to_out[1](attention_output) + + return attention_output + + +# time step conditioning embedding +class SinusPositionEmbedding(nn.Module): + def __init__(self, dim): + super().__init__() + self.dim = dim + + def forward(self, hidden_states, scale=1000): + device = hidden_states.device + half_dim = self.dim // 2 + emb = math.log(10000) / (half_dim - 1) + emb = torch.exp(torch.arange(half_dim, device=device).float() * -emb) + emb = scale * hidden_states.unsqueeze(1) * emb.unsqueeze(0) + emb = torch.cat((emb.sin(), emb.cos()), dim=-1) + return emb.type_as(hidden_states) + + +class DiTTimestepEmbedding(nn.Module): + def __init__(self, dim, freq_embed_dim=256): + super().__init__() + self.time_embed = SinusPositionEmbedding(freq_embed_dim) + self.time_mlp = nn.ModuleList([nn.Linear(freq_embed_dim, dim), nn.SiLU(), nn.Linear(dim, dim)]) + + def forward(self, timestep): + time_hidden = self.time_embed(timestep) + time_hidden = time_hidden.to(timestep.dtype) + for layer in self.time_mlp: + time_hidden = layer(time_hidden) # b d + return time_hidden + + +class DiTDecoderLayer(nn.Module): + def __init__(self, config: Qwen2_5OmniDiTConfig, look_ahead_block=0, look_backward_block=0): + super().__init__() + self.attn_norm = Qwen2_5_OmniAdaLayerNormZero(config.hidden_size) + + self.attn = DiTAttention(config) + self.look_ahead_block = look_ahead_block + self.look_backward_block = look_backward_block + self.ff_norm = nn.LayerNorm(config.hidden_size, elementwise_affine=False, eps=1e-6) + self.ff = DiTMLP(dim=config.hidden_size, mult=config.ff_mult, dropout=config.dropout) + + def forward( + self, hidden_states, timestep, position_embeddings=None, block_diff=None + ): # x: noised input, t: time embedding + # pre-norm & modulation for attention input + norm, gate_msa, shift_mlp, scale_mlp, gate_mlp = self.attn_norm(hidden_states, emb=timestep) + + # attention + attn_output = self.attn( + hidden_states=norm, + position_embeddings=position_embeddings, + attention_mask=(block_diff >= -float(self.look_backward_block)) + & (block_diff <= float(self.look_ahead_block)), + ) + + # process attention output for input x + hidden_states = hidden_states + gate_msa.unsqueeze(1) * attn_output + + norm = self.ff_norm(hidden_states) * (1 + scale_mlp[:, None]) + shift_mlp[:, None] + ff_output = self.ff(norm) + hidden_states = hidden_states + gate_mlp.unsqueeze(1) * ff_output + + return hidden_states + + +class SnakeBeta(nn.Module): + """ + A modified Snake function which uses separate parameters for the magnitude of the periodic components + Shape: + - Input: (B, C, T) + - Output: (B, C, T), same shape as the input + Parameters: + - alpha - trainable parameter that controls frequency + - beta - trainable parameter that controls magnitude + References: + - This activation function is a modified version based on this paper by Liu Ziyin, Tilman Hartwig, Masahito Ueda: + https://huggingface.co/papers/2006.08195 + """ + + def __init__(self, in_features, alpha=1.0): + super().__init__() + self.in_features = in_features + + # initialize alpha + self.alpha = Parameter(torch.zeros(in_features) * alpha) + self.beta = Parameter(torch.zeros(in_features) * alpha) + + self.no_div_by_zero = 0.000000001 + + def forward(self, hidden_states): + """ + Forward pass of the function. + Applies the function to the input elementwise. + SnakeBeta ∶= x + 1/b * sin^2 (xa) + """ + alpha = self.alpha.unsqueeze(0).unsqueeze(-1) # line up with x to [B, C, T] + beta = self.beta.unsqueeze(0).unsqueeze(-1) + alpha = torch.exp(alpha) + beta = torch.exp(beta) + hidden_states = hidden_states + (1.0 / (beta + self.no_div_by_zero)) * torch.pow( + torch.sin(hidden_states * alpha), 2 + ) + + return hidden_states + + +class UpSample1d(nn.Module): + def __init__(self, ratio=2, kernel_size=None): + super().__init__() + self.ratio = ratio + self.kernel_size = int(6 * ratio // 2) * 2 if kernel_size is None else kernel_size + self.stride = ratio + self.pad = self.kernel_size // ratio - 1 + self.pad_left = self.pad * self.stride + (self.kernel_size - self.stride) // 2 + self.pad_right = self.pad * self.stride + (self.kernel_size - self.stride + 1) // 2 + + filter = kaiser_sinc_filter1d(cutoff=0.5 / ratio, half_width=0.6 / ratio, kernel_size=self.kernel_size) + self.register_buffer("filter", filter, persistent=False) + + def forward(self, hidden_states): + channels = hidden_states.shape[1] + + hidden_states = F.pad(hidden_states, (self.pad, self.pad), mode="replicate") + hidden_states = self.ratio * F.conv_transpose1d( + hidden_states, self.filter.expand(channels, -1, -1), stride=self.stride, groups=channels + ) + hidden_states = hidden_states[..., self.pad_left : -self.pad_right] + + return hidden_states + + +class DownSample1d(nn.Module): + def __init__(self, ratio=2, kernel_size=None): + super().__init__() + cutoff = 0.5 / ratio + half_width = 0.6 / ratio + self.cutoff = cutoff + self.half_width = half_width + self.kernel_size = kernel_size + + if cutoff < 0.0: + raise ValueError("Minimum cutoff must be larger than zero.") + if cutoff > 0.5: + raise ValueError("A cutoff above 0.5 does not make sense.") + + self.even = kernel_size % 2 == 0 + self.pad_left = kernel_size // 2 - int(self.even) + self.pad_right = kernel_size // 2 + self.stride = ratio + filter = kaiser_sinc_filter1d(cutoff, half_width, kernel_size) + self.register_buffer("filter", filter, persistent=False) + + def forward(self, hidden_states): + channels = hidden_states.shape[1] + hidden_states = F.pad(hidden_states, (self.pad_left, self.pad_right), mode="replicate") + out = F.conv1d(hidden_states, self.filter.expand(channels, -1, -1), stride=self.stride, groups=channels) + return out + + +class TorchActivation1d(nn.Module): + def __init__( + self, + activation, + up_ratio: int = 2, + down_ratio: int = 2, + up_kernel_size: int = 12, + down_kernel_size: int = 12, + ): + super().__init__() + if not callable(activation): + raise TypeError("Activation function must be callable") + self.act = activation + self.upsample = UpSample1d(up_ratio, up_kernel_size) + self.downsample = DownSample1d(down_ratio, down_kernel_size) + + def forward(self, hidden_states): + hidden_states = self.upsample(hidden_states) + hidden_states = self.act(hidden_states) + hidden_states = self.downsample(hidden_states) + + return hidden_states + + +class AMPBlock(torch.nn.Module): + def __init__( + self, + channels, + kernel_size=3, + dilation=(1, 3, 5), + ): + super().__init__() + + self.convs1 = nn.ModuleList( + [ + nn.Conv1d( + channels, + channels, + kernel_size, + 1, + dilation=dilation[0], + padding=self._get_padding(kernel_size, dilation[0]), + ), + nn.Conv1d( + channels, + channels, + kernel_size, + 1, + dilation=dilation[1], + padding=self._get_padding(kernel_size, dilation[1]), + ), + nn.Conv1d( + channels, + channels, + kernel_size, + 1, + dilation=dilation[2], + padding=self._get_padding(kernel_size, dilation[2]), + ), + ] + ) + + self.convs2 = nn.ModuleList( + [ + nn.Conv1d( + channels, + channels, + kernel_size, + 1, + dilation=1, + padding=self._get_padding(kernel_size, 1), + ), + nn.Conv1d( + channels, + channels, + kernel_size, + 1, + dilation=1, + padding=self._get_padding(kernel_size, 1), + ), + nn.Conv1d( + channels, + channels, + kernel_size, + 1, + dilation=1, + padding=self._get_padding(kernel_size, 1), + ), + ] + ) + + self.num_layers = len(self.convs1) + len(self.convs2) # total number of conv layers + + self.activations = nn.ModuleList( + [TorchActivation1d(activation=SnakeBeta(channels)) for _ in range(self.num_layers)] + ) + + def _get_padding(self, kernel_size, dilation=1): + return int((kernel_size * dilation - dilation) / 2) + + def forward(self, hidden_states): + acts1, acts2 = self.activations[::2], self.activations[1::2] + for conv1, conv2, act1, act2 in zip(self.convs1, self.convs2, acts1, acts2): + residual = hidden_states + hidden_states = act1(hidden_states) + hidden_states = conv1(hidden_states) + hidden_states = act2(hidden_states) + hidden_states = conv2(hidden_states) + hidden_states = residual + hidden_states + + return hidden_states + + +@auto_docstring( + custom_intro=""" + The full Qwen2.5Omni Token2WavBigVGAN model. Which take mel spectrogram as input and predict waveform. + """ +) +class Qwen2_5OmniToken2WavBigVGANModel(Qwen2_5OmniPreTrainedModel): + config: Qwen2_5OmniBigVGANConfig + input_modalities = "audio" + + def __init__(self, config: Qwen2_5OmniBigVGANConfig): + super().__init__(config) + self.num_residual_blocks = len(config.resblock_kernel_sizes) + self.num_upsample_layers = len(config.upsample_rates) + + self.conv_pre = nn.Conv1d(config.mel_dim, config.upsample_initial_channel, 7, 1, padding=3) + + # Removing extra ModuleList breaks official state dict + ups = [ + nn.ModuleList( + [ + nn.ConvTranspose1d( + config.upsample_initial_channel // (2**layer_idx), + config.upsample_initial_channel // (2 ** (layer_idx + 1)), + kernel_size, + stride, + padding=(kernel_size - stride) // 2, + ) + ] + ) + for layer_idx, (stride, kernel_size) in enumerate(zip(config.upsample_rates, config.upsample_kernel_sizes)) + ] + self.ups = nn.ModuleList(ups) + + self.resblocks = nn.ModuleList( + [ + AMPBlock(config.upsample_initial_channel // (2 ** (layer_idx + 1)), kernel_size, dilation) + for layer_idx in range(self.num_upsample_layers) + for kernel_size, dilation in zip(config.resblock_kernel_sizes, config.resblock_dilation_sizes) + ] + ) + + self.activation_post = TorchActivation1d( + activation=SnakeBeta(config.upsample_initial_channel // (2**self.num_upsample_layers)) + ) + self.conv_post = nn.Conv1d( + config.upsample_initial_channel // (2**self.num_upsample_layers), 1, 7, 1, padding=3, bias=False + ) + + self.post_init() + + def normalize_spectrogram(self, spectrogram, max_value, min_db): + return torch.clamp((2 * max_value) * ((spectrogram - min_db) / (-min_db)) - max_value, -max_value, max_value) + + def amplitude_to_db(self, amplitude, min_db_level): + min_level = torch.exp( + torch.tensor(min_db_level / 20.0 * np.log(10), device=amplitude.device, dtype=amplitude.dtype) + ) + return 20 * torch.log10(torch.clamp(amplitude, min=min_level)) + + def process_mel_spectrogram(self, mel_spectrogram): + amplitude_spectrum = torch.exp(mel_spectrogram) + decibel_spectrum = self.amplitude_to_db(amplitude_spectrum, -115) - 20 + return self.normalize_spectrogram(decibel_spectrum, 1, -115) + + def forward(self, mel_spectrogram, **kwargs): + processed_spectrogram = self.process_mel_spectrogram(mel_spectrogram) + hidden_representation = self.conv_pre(processed_spectrogram) + + for layer_index in range(self.num_upsample_layers): + hidden_representation = self.ups[layer_index][0](hidden_representation) + residual_output = sum( + self.resblocks[layer_index * self.num_residual_blocks + block_index](hidden_representation) + for block_index in range(self.num_residual_blocks) + ) + residual_output = residual_output / self.num_residual_blocks + hidden_representation = residual_output + + hidden_representation = self.activation_post(hidden_representation) + output_waveform = self.conv_post(hidden_representation) + return torch.clamp(output_waveform, min=-1.0, max=1.0).squeeze().cpu() + + +class RungeKutta4ODESolver: + def __init__(self, function, initial_value): + self.function = function + self.initial_value = initial_value + + self._one_third = 1 / 3 + self._two_thirds = 2 / 3 + + def _rk4_step(self, function, time_start, time_step, time_end, value_start, function_value_start=None): + k1 = function_value_start if function_value_start is not None else function(time_start, value_start) + k2 = function(time_start + time_step * self._one_third, value_start + time_step * k1 * self._one_third) + k3 = function(time_start + time_step * self._two_thirds, value_start + time_step * (k2 - k1 * self._one_third)) + k4 = function(time_end, value_start + time_step * (k1 - k2 + k3)) + return (k1 + 3 * (k2 + k3) + k4) * time_step / 8 + + def _compute_step(self, function, time_start, time_step, time_end, value_start): + function_value_start = function(time_start, value_start) + return self._rk4_step( + function, time_start, time_step, time_end, value_start, function_value_start=function_value_start + ), function_value_start + + def _linear_interpolation(self, time_start, time_end, value_start, value_end, time_point): + if time_point == time_start: + return value_start + if time_point == time_end: + return value_end + weight = (time_point - time_start) / (time_end - time_start) + return value_start + weight * (value_end - value_start) + + def integrate(self, time_points): + solution = torch.empty( + len(time_points), + *self.initial_value.shape, + dtype=self.initial_value.dtype, + device=self.initial_value.device, + ) + solution[0] = self.initial_value + + current_index = 1 + current_value = self.initial_value + for time_start, time_end in zip(time_points[:-1], time_points[1:]): + time_step = time_end - time_start + delta_value, _ = self._compute_step(self.function, time_start, time_step, time_end, current_value) + next_value = current_value + delta_value + + while current_index < len(time_points) and time_end >= time_points[current_index]: + solution[current_index] = self._linear_interpolation( + time_start, time_end, current_value, next_value, time_points[current_index] + ) + current_index += 1 + + current_value = next_value + + return solution + + +@auto_docstring( + custom_intro=""" + The full Qwen2.5Omni Token2WavDiT model. Which take speech tokens as input and predict mel spectrogram. + """ +) +class Qwen2_5OmniToken2WavDiTModel(Qwen2_5OmniPreTrainedModel): + config: Qwen2_5OmniDiTConfig + input_modalities = "audio" + _no_split_modules = ["DiTDecoderLayer"] + + def __init__(self, config: Qwen2_5OmniDiTConfig): + super().__init__(config) + self.mel_dim = config.mel_dim + self.repeats = config.repeats + self.time_embed = DiTTimestepEmbedding(config.hidden_size) + + self.text_embed = DiTCodecEmbedding(config.num_embeds, config.emb_dim, config.repeats) + self.input_embed = DiTInputEmbedding(config) + + self.rotary_embed = Qwen2_5OmniDiTRotaryEmbedding(config=config) + + self.hidden_size = config.hidden_size + self.layers = config.num_hidden_layers + self.block_size = config.block_size + self.num_attention_heads = config.num_attention_heads + + self.transformer_blocks = nn.ModuleList() + for i in range(config.num_hidden_layers): + self.transformer_blocks.append( + DiTDecoderLayer( + config, + look_ahead_block=1 if i in config.look_ahead_layers else 0, + look_backward_block=1 if i in config.look_backward_layers else 0, + ) + ) + + self.norm_out = Qwen2_5_OmniAdaLayerNormZero_Final(config.hidden_size) # final modulation + self.proj_out = nn.Linear(config.hidden_size, config.mel_dim) + + self.post_init() + + def _create_block_diff(self, hidden_states): + batch, seq_len = hidden_states.shape[0], hidden_states.shape[1] + block_indices = torch.arange(seq_len, device=hidden_states.device) // self.block_size # [seq_length] + + block_i = block_indices.unsqueeze(1) # [seq_length, 1] + block_j = block_indices.unsqueeze(0) # [1, seq_length] + block_diff = block_j - block_i # (n, n) + + return block_diff.expand(batch, self.num_attention_heads, seq_len, seq_len) + + def forward( + self, + hidden_states, + condition_vector, + speaker_embedding, + quantized_code, + time_step, + drop_audio_conditioning=False, + drop_code=False, + apply_cfg=True, + **kwargs, + ): + batch_size = hidden_states.shape[0] + if time_step.ndim == 0: + time_step = time_step.repeat(batch_size) + + # Compute embeddings + time_embedding = self.time_embed(time_step) + text_embedding = self.text_embed(quantized_code, drop_code=False if apply_cfg else drop_code) + text_embedding_unconditioned = self.text_embed(quantized_code, drop_code=True) if apply_cfg else None + + hidden_states = self.input_embed( + hidden_states, + speaker_embedding, + condition_vector, + text_embedding, + drop_audio_cond=drop_audio_conditioning, + code_embed_uncond=text_embedding_unconditioned, + apply_cfg=apply_cfg, + ) + + # Compute positional encodings + position_ids = torch.arange(hidden_states.shape[1], device=hidden_states.device) + position_ids = position_ids[None, :].repeat(batch_size, 1) + position_embeddings = self.rotary_embed(hidden_states, position_ids) + blockwise_difference = self._create_block_diff(hidden_states) + + # Transformer blocks + for transformer_block in self.transformer_blocks: + hidden_states = transformer_block( + hidden_states, + time_embedding, + position_embeddings=position_embeddings, + block_diff=blockwise_difference, + ) + + hidden_states = self.norm_out(hidden_states, time_embedding) + output = self.proj_out(hidden_states) + + return output + + @torch.no_grad() + def sample( + self, + conditioning_vector, + reference_mel_spectrogram, + quantized_code, + num_steps=10, + guidance_scale=0.5, + sway_coefficient=-1.0, + ): + maximum_duration = quantized_code.shape[1] * self.repeats + batch_size = reference_mel_spectrogram.shape[0] + if batch_size != 1: + raise ValueError("Only batch size = 1 is currently supported") + + if maximum_duration > self.config.max_position_embeddings: + raise ValueError( + f"Requested mel length ({maximum_duration}) exceeds `dit_config.max_position_embeddings` " + f"({self.config.max_position_embeddings}). Provide shorter `quantized_code`." + ) + + initial_state = torch.randn( + [batch_size, maximum_duration, self.mel_dim], + dtype=reference_mel_spectrogram.dtype, + device=quantized_code.device, + ) + conditioning_vector = conditioning_vector.unsqueeze(1).repeat(1, maximum_duration, 1) + + def ode_function(time_step, hidden_states): + if guidance_scale < 1e-5: + prediction = self( + hidden_states=hidden_states, + speaker_embedding=conditioning_vector, + condition_vector=reference_mel_spectrogram, + quantized_code=quantized_code, + time_step=time_step, + drop_audio_conditioning=False, + drop_code=False, + apply_cfg=False, + ) + return prediction + + model_output = self( + hidden_states=hidden_states, + quantized_code=quantized_code, + speaker_embedding=conditioning_vector, + condition_vector=reference_mel_spectrogram, + time_step=time_step, + apply_cfg=True, + ) + guided_prediction, null_prediction = torch.chunk(model_output, 2, dim=0) + return guided_prediction + (guided_prediction - null_prediction) * guidance_scale + + initial_time = 0 + time_embedding = torch.linspace( + initial_time, 1, num_steps, device=quantized_code.device, dtype=conditioning_vector.dtype + ) + + if sway_coefficient is not None: + time_embedding += sway_coefficient * (torch.cos(torch.pi / 2 * time_embedding) - 1 + time_embedding) + + ode_solver = RungeKutta4ODESolver(function=ode_function, initial_value=initial_state) + solution_trajectory = ode_solver.integrate(time_embedding) + + generated_waveform = solution_trajectory[-1] + generated_mel_spectrogram = generated_waveform.permute(0, 2, 1) + return generated_mel_spectrogram + + +@auto_docstring( + custom_intro=""" + The full Qwen2.5Omni Token2Wav model. Consists a DiT model take speech tokens as input and predict mel spectrogram and a BigVGAN vocoder take mel spectrogram as input and predict waveform. + """ +) +class Qwen2_5OmniToken2WavModel(Qwen2_5OmniPreTrainedModel): + config: Qwen2_5OmniToken2WavConfig + base_model_prefix = "model" + input_modalities = "audio" + _no_split_modules = ["Qwen2_5OmniToken2WavDiTModel", "Qwen2_5OmniToken2WavBigVGANModel"] + + def __init__(self, config: Qwen2_5OmniToken2WavConfig): + super().__init__(config) + attn_impl = config._attn_implementation + if is_flash_attention_requested(config): + logger.warning_once( + "Qwen2_5OmniToken2WavModel must inference with fp32, but Flash Attention only supports fp16 and bf16, " + "attention implementation of Qwen2_5OmniToken2WavModel will fallback to sdpa." + ) + attn_impl = "sdpa" + elif config._attn_implementation == "eager": + logger.warning_once( + "Qwen2_5OmniToken2WavModel does not support eager attention implementation, fall back to sdpa" + ) + attn_impl = "sdpa" + self.code2wav_dit_model = Qwen2_5OmniToken2WavDiTModel._from_config( + config.dit_config, attn_implementation=attn_impl + ) + self.code2wav_bigvgan_model = Qwen2_5OmniToken2WavBigVGANModel._from_config( + config.bigvgan_config, attn_implementation=attn_impl + ) + + self.post_init() + + def forward( + self, + code, + conditioning, + reference_mel, + num_steps=10, + guidance_scale=0.5, + sway_coefficient=-1.0, + **kwargs, + ): + """Generates a waveform from input code and conditioning parameters.""" + + mel_spectrogram = self.code2wav_dit_model.sample( + conditioning, + reference_mel, + code, + num_steps=num_steps, + guidance_scale=guidance_scale, + sway_coefficient=sway_coefficient, + ) + + waveform = self.code2wav_bigvgan_model(mel_spectrogram) + + return waveform + + +############################ +# Start Qwen2.5Omni # +############################ + + +@auto_docstring( + custom_intro=""" + The full Qwen2.5Omni model, a multimodal model composed of 3 sub-models: + - [`Qwen2_5OmniThinkerForConditionalGeneration`]: + a causal auto-regressive transformer takes text, audio, image, video as input and predict text tokens. + - [`Qwen2_5OmniTalkerForConditionalGeneration`]: + a causal auto-regressive transformer takes thinker hidden states and response as input and predict speech tokens. + - [`Qwen2_5OmniToken2WavModel`]: + a DiT model take speech tokens as input and predict mel spectrogram and a BigVGAN vocoder take mel spectrogram as input and predict waveform. + """ +) +class Qwen2_5OmniForConditionalGeneration(Qwen2_5OmniPreTrainedModel, GenerationMixin): + config: Qwen2_5OmniConfig + output_modalities = ("audio", "text") + _no_split_modules = [ + "Qwen2_5OmniTalkerForConditionalGeneration", + "Qwen2_5OmniToken2WavModel", + ] + + def __init__(self, config): + super().__init__(config) + + self.thinker = Qwen2_5OmniThinkerForConditionalGeneration(config.thinker_config) + + self.has_talker = config.enable_audio_output + self.speaker_map = {} + if config.enable_audio_output: + self.enable_talker() + self.post_init() + + def enable_talker(self): + self.talker = Qwen2_5OmniTalkerForConditionalGeneration(self.config.talker_config) + self.token2wav = Qwen2_5OmniToken2WavModel(self.config.token2wav_config) + self.token2wav.float() + self.has_talker = True + + def load_speakers(self, path): + check_torch_load_is_safe() + for key, value in torch.load(path, weights_only=True).items(): + self.speaker_map[key] = value + logger.info(f"Speaker {list(self.speaker_map.keys())} loaded") + + def disable_talker(self): + if hasattr(self, "talker"): + del self.talker + if hasattr(self, "token2wav"): + del self.token2wav + self.has_talker = False + + @classmethod + def from_pretrained( + cls, + pretrained_model_name_or_path, + *model_args, + config=None, + cache_dir=None, + ignore_mismatched_sizes=False, + force_download=False, + local_files_only=False, + token=None, + revision="main", + use_safetensors=None, + weights_only=True, + **kwargs, + ): + model = super().from_pretrained( + pretrained_model_name_or_path, + *model_args, + config=config, + cache_dir=cache_dir, + ignore_mismatched_sizes=ignore_mismatched_sizes, + force_download=force_download, + local_files_only=local_files_only, + token=token, + revision=revision, + use_safetensors=use_safetensors, + weights_only=weights_only, + **kwargs, + ) + spk_path = cached_file( + pretrained_model_name_or_path, + "spk_dict.pt", + subfolder=kwargs.pop("subfolder", None), + cache_dir=kwargs.pop("cache_dir", None), + force_download=kwargs.pop("force_download", False), + proxies=kwargs.pop("proxies", None), + local_files_only=kwargs.pop("local_files_only", False), + token=token, + revision=kwargs.pop("revision", None), + ) + if spk_path is None: + raise ValueError(f"""{pretrained_model_name_or_path}/{spk_path} not exists""") + model.load_speakers(spk_path) + + return model + + @torch.no_grad() + @deprecate_kwarg("return_audio", version="v5", new_name="generation_mode") + # TODO: raushan, defaults should be saved in generation config + def generate( + self, + input_ids: torch.Tensor | None = None, + speaker: str = "Chelsie", + use_audio_in_video: bool = False, + thinker_max_new_tokens: int = 1024, + talker_max_new_tokens: int = 4096, + talker_do_sample: bool = True, + talker_top_k: int = 40, + talker_top_p: float = 0.8, + talker_temperature: float = 0.9, + talker_eos_token_id: list[int] = [8292, 8294], + talker_repetition_penalty: float = 1.05, + **kwargs, + ): + r""" + Generate text response and audio from input. + + Args: + input_ids (`Optional[torch.Tensor]`, *optional*): + Input ids, should obtain from processor. + speaker (`str` , defaults to "Chelsie"): + Which speaker should be used in audio response. + use_audio_in_video (`bool`, defaults to False): + Whether or not use audio track in video, should same as the parameter in `process_audio_info`. + generation_mode (`Optional[str]`, *optional*): + Whether or not return response in audio format. When `generation_mode="audio"`, this parameter is same as `config.enable_audio_output`. + kwargs (*optional*): + - Without a prefix, they will be entered as `**kwargs` for the `generate` method of each sub-model. + - With a *thinker_*, *talker_*, *token2wav_* prefix, they will be input for the `generate` method of the + thinker, talker and token2wav respectively. It has the priority over the keywords without a prefix. + Returns: + When `return_audio=False`: + - **Text** (`torch.Tensor`): Generated text token sequence. + When `return_audio=True`: + - **Text** (`torch.Tensor`): Generated text token sequence. + - **Audio waveform** (`torch.Tensor`): Generated audio waveform. + """ + # check `False` on purpose because the parameter can be `str/bool`. This is needed for BC + generation_mode = kwargs.pop("generation_mode", None) + return_audio = generation_mode != "text" and generation_mode is not False + + if speaker not in self.speaker_map: + raise ValueError(f"{speaker} is not available, available speakers: {self.speaker_map.keys()}") + if return_audio and not self.has_talker: + raise ValueError( + "Cannot use talker when talker module not initialized. Use `enable_talker` method or set enable_talker in config to enable talker." + ) + if return_audio is None: + return_audio = self.has_talker + if input_ids.shape[0] != 1 and return_audio: + raise NotImplementedError("Qwen2.5-Omni currently does not support batched inference with audio output") + + shared_kwargs = {"use_audio_in_video": use_audio_in_video} + thinker_kwargs = { + "max_new_tokens": thinker_max_new_tokens, + } + talker_kwargs = { + "max_new_tokens": talker_max_new_tokens, + "do_sample": talker_do_sample, + "top_k": talker_top_k, + "top_p": talker_top_p, + "temperature": talker_temperature, + "eos_token_id": talker_eos_token_id, + "repetition_penalty": talker_repetition_penalty, + } + token2wav_kwargs = {} + + for key, value in kwargs.items(): + if key.startswith("thinker_"): + thinker_kwargs[key[len("thinker_") :]] = value + elif key.startswith("talker_"): + talker_kwargs[key[len("talker_") :]] = value + elif key.startswith("token2wav_"): + token2wav_kwargs[key[len("token2wav_") :]] = value + # Process special input values + elif key == "feature_attention_mask": + thinker_kwargs[key] = value + talker_kwargs["audio_feature_lengths"] = torch.sum(value, dim=1) + elif key == "input_features" or key == "attention_mask": + thinker_kwargs[key] = value + # Put other key to shared kwargs + else: + shared_kwargs[key] = value + + # Merge kwargs + for key, value in shared_kwargs.items(): + if key not in thinker_kwargs: + thinker_kwargs[key] = value + if key not in talker_kwargs: + talker_kwargs[key] = value + if key not in token2wav_kwargs: + token2wav_kwargs[key] = value + speaker_params = self.speaker_map[speaker] + + # 1. Generate from thinker module + generate_audio = return_audio and self.has_talker + if generate_audio: + thinker_kwargs["output_hidden_states"] = True + thinker_kwargs["return_dict_in_generate"] = True + + thinker_result = self.thinker.generate(input_ids=input_ids, **thinker_kwargs) + + if not generate_audio: + return thinker_result + + # 2. Generate speech tokens from talker module + embeds_to_talker = thinker_result.hidden_states[0][0].clone().to(input_ids.device) + if thinker_kwargs.get("input_features") is not None: + audio_ids_mask = input_ids == self.config.thinker_config.audio_token_index + audio_mask = audio_ids_mask.unsqueeze(-1).expand_as(embeds_to_talker) + audio_mask_tensor = torch.zeros( + [audio_ids_mask.sum(), embeds_to_talker.shape[-1]], + dtype=embeds_to_talker.dtype, + device=input_ids.device, + ) + embeds_to_talker.masked_scatter_(audio_mask, audio_mask_tensor) + if thinker_kwargs.get("pixel_values") is not None: + image_ids_mask = input_ids == self.config.thinker_config.image_token_index + image_mask = image_ids_mask.unsqueeze(-1).expand_as(embeds_to_talker) + image_mask_tensor = torch.zeros( + [image_ids_mask.sum(), embeds_to_talker.shape[-1]], + dtype=embeds_to_talker.dtype, + device=input_ids.device, + ) + embeds_to_talker.masked_scatter_(image_mask, image_mask_tensor) + if thinker_kwargs.get("pixel_values_videos") is not None: + video_ids_mask = input_ids == self.config.thinker_config.video_token_index + video_mask = video_ids_mask.unsqueeze(-1).expand_as(embeds_to_talker) + video_mask_tensor = torch.zeros( + [video_ids_mask.sum(), embeds_to_talker.shape[-1]], + dtype=embeds_to_talker.dtype, + device=input_ids.device, + ) + embeds_to_talker.masked_scatter_(video_mask, video_mask_tensor) + + processed_thinker_hidden = ( + (embeds_to_talker,) + thinker_result.hidden_states[0][1:], + ) + thinker_result.hidden_states[1:] + thinker_generate_ids = thinker_result.sequences[:, input_ids.size(1) :].to(input_ids.device) + thinker_token_embeds = [ + token_hidden_states[0].to(input_ids.device) for token_hidden_states in processed_thinker_hidden + ] + thinker_hidden_states = [ + token_hidden_states[-1].to(input_ids.device) for token_hidden_states in processed_thinker_hidden + ] + + talker_text_bos_token = speaker_params["bos_token"] + talker_input_text_ids = torch.cat( + [ + input_ids, + torch.tensor([[talker_text_bos_token]], dtype=torch.long, device=input_ids.device), + thinker_generate_ids[:, :1], + ], + dim=-1, + ) + + talker_input_ids = torch.cat( + [ + torch.full_like(input_ids, fill_value=self.talker.codec_mask_token), + torch.tensor([[self.talker.codec_pad_token]], dtype=torch.long, device=input_ids.device), + torch.tensor([[self.talker.codec_bos_token]], dtype=torch.long, device=input_ids.device), + ], + dim=1, + ) + + thinker_embed_tokens = self.thinker.get_input_embeddings() + thinker_reply_part = torch.cat(thinker_hidden_states[1:], dim=1) + torch.cat(thinker_token_embeds[1:], dim=1) + talker_inputs_embeds = thinker_hidden_states[0] + thinker_token_embeds[0] + talker_text_bos_token = torch.tensor([[talker_text_bos_token]], dtype=torch.long, device=input_ids.device) + talker_text_bos_embed = thinker_embed_tokens(talker_text_bos_token).to(input_ids.device) + talker_inputs_embeds = torch.cat( + [ + talker_inputs_embeds, + talker_text_bos_embed, + thinker_reply_part[:, :1, :], + ], + dim=1, + ) + + eos_token = torch.tensor([[self.talker.text_eos_token]], dtype=torch.long, device=input_ids.device) + eos_embedding = thinker_embed_tokens(eos_token).to(input_ids.device) + + pad_token = torch.tensor([[self.talker.text_pad_token]], dtype=torch.long, device=input_ids.device) + pad_embedding = thinker_embed_tokens(pad_token).to(input_ids.device) + + thinker_reply_part = torch.cat( + [ + thinker_reply_part[:, 1:, :], + eos_embedding, + pad_embedding, + ], + dim=1, + ) + + talker_attention_mask = None + if "attention_mask" in kwargs: + talker_attention_mask = torch.cat( + [kwargs["attention_mask"], kwargs["attention_mask"].new_ones((1, 2))], dim=1 + ).to(input_ids.device) + + talker_result = self.talker.generate( + input_ids=talker_input_ids, + input_text_ids=talker_input_text_ids, + thinker_reply_part=thinker_reply_part, + inputs_embeds=talker_inputs_embeds, + attention_mask=talker_attention_mask, + suppress_tokens=[self.talker.codec_bos_token], + **{k: (v.to(input_ids.device) if torch.is_tensor(v) else v) for k, v in talker_kwargs.items()}, + ) + talker_generate_codes = talker_result[:, talker_input_ids.shape[1] : -1] + + # 3. Generate wavs from code + if self.token2wav.dtype != torch.float: + self.token2wav.float() + + wav = self.token2wav( + talker_generate_codes.to(input_ids.device), + conditioning=speaker_params["cond"].to(input_ids.device).float(), + reference_mel=speaker_params["ref_mel"].to(input_ids.device).float(), + **token2wav_kwargs, + ) + + return thinker_result.sequences, wav.float() + + +__all__ = [ + "Qwen2_5OmniForConditionalGeneration", + "Qwen2_5OmniThinkerTextModel", + "Qwen2_5OmniThinkerForConditionalGeneration", + "Qwen2_5OmniTalkerModel", + "Qwen2_5OmniTalkerForConditionalGeneration", + "Qwen2_5OmniToken2WavDiTModel", + "Qwen2_5OmniToken2WavBigVGANModel", + "Qwen2_5OmniToken2WavModel", + "Qwen2_5OmniPreTrainedModel", + "Qwen2_5OmniPreTrainedModelForConditionalGeneration", +] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/qwen2_5_omni/modular_qwen2_5_omni.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/qwen2_5_omni/modular_qwen2_5_omni.py new file mode 100644 index 0000000000000000000000000000000000000000..027189f919ad7a2748adaec07a7157962b649b1d --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/qwen2_5_omni/modular_qwen2_5_omni.py @@ -0,0 +1,4280 @@ +# Copyright 2025 The Qwen team, Alibaba Group and the HuggingFace Inc. team. All rights reserved. +# +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""PyTorch Qwen2.5Omni model (Audio, Image, Video).""" + +import math +from collections.abc import Callable +from dataclasses import dataclass +from typing import Any, Optional + +import numpy as np +import torch +import torch.nn.functional as F +from torch import nn +from torch.nn import Parameter + +from ... import initialization as init +from ...cache_utils import Cache +from ...configuration_utils import PreTrainedConfig, layer_type_validation +from ...generation import GenerationMixin +from ...modeling_outputs import BaseModelOutputWithPooling, ModelOutput +from ...modeling_rope_utils import RopeParameters +from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel +from ...processing_utils import Unpack +from ...utils import ( + TransformersKwargs, + auto_docstring, + can_return_tuple, + check_torch_load_is_safe, + logging, + torch_compilable_check, +) +from ...utils.deprecation import deprecate_kwarg +from ...utils.generic import is_flash_attention_requested, merge_with_config_defaults +from ...utils.hub import cached_file +from ...utils.output_capturing import capture_outputs +from ..llama.modeling_llama import LlamaRotaryEmbedding, rotate_half +from ..qwen2_5_vl.configuration_qwen2_5_vl import Qwen2_5_VLVisionConfig +from ..qwen2_5_vl.modeling_qwen2_5_vl import ( + Qwen2_5_VisionRotaryEmbedding, + Qwen2_5_VisionTransformerPretrainedModel, + Qwen2_5_VLAttention, + Qwen2_5_VLMLP, + Qwen2_5_VLPreTrainedModel, + Qwen2_5_VLTextModel, + Qwen2_5_VLVisionBlock, + eager_attention_forward, +) +from ..qwen2_audio.configuration_qwen2_audio import Qwen2AudioEncoderConfig +from ..qwen2_audio.modeling_qwen2_audio import Qwen2AudioEncoderLayer +from ..qwen2_vl.modeling_qwen2_vl import Qwen2VLRotaryEmbedding + + +logger = logging.get_logger(__name__) + + +class Qwen2_5OmniVisionEncoderConfig(Qwen2_5_VLVisionConfig): + r""" + This is the configuration class to store the configuration of a [`Qwen2_5OmniThinkerVision`]. It is used to instantiate a + Qwen2.5-VL vision encoder according to the specified arguments, defining the model architecture. Instantiating a + configuration with the defaults will yield a similar configuration to that of the audio encoder of the Qwen2.5-VL + architecture. + + e.g. [Qwen/Qwen2.5-Omni-7B](https://huggingface.co/Qwen/Qwen2.5-Omni-7B) + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + depth (`int`, *optional*, defaults to 32): + Number of layers (depth) in the model. + hidden_size (`int`, *optional*, defaults to 3584): + The size of the hidden layers. + hidden_act (`str`, *optional*, defaults to `"quick_gelu"`): + The non-linear activation function used in the model. Supported options include `"quick_gelu"` and others as applicable. + mlp_ratio (`float`, *optional*, defaults to 4): + The ratio used to determine the size of the MLP (Multi-Layer Perceptron) hidden layer. + num_heads (`int`, *optional*, defaults to 16): + Number of attention heads for each attention layer. + in_channels (`int`, *optional*, defaults to 3): + Number of input channels. + patch_size (`int`, *optional*, defaults to 14): + The size of the patches extracted from the input. + spatial_merge_size (`int`, *optional*, defaults to 2): + The size used for merging spatial dimensions. + temporal_patch_size (`int`, *optional*, defaults to 2): + The size used for patches along the temporal dimension. + + Example: + + ```python + >>> from transformers import Qwen2_5OmniVisionEncoderConfig, Qwen2_5OmniVisionEncoder + + >>> # Initializing a Qwen2_5OmniVisionEncoderConfig + >>> configuration = Qwen2_5OmniVisionEncoderConfig() + + >>> # Initializing a Qwen2_5OmniVisionEncoder (with random weights) + >>> model = Qwen2_5OmniVisionEncoder(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "qwen2_5_omni_vision_encoder" + + def __init__( + self, + depth=32, + hidden_size=3584, + hidden_act="silu", + intermediate_size=3420, + num_heads=16, + in_channels=3, + patch_size=14, + spatial_merge_size=2, + temporal_patch_size=2, + window_size=112, + out_hidden_size=3584, + fullatt_block_indexes=[7, 15, 23, 31], + initializer_range=0.02, + **kwargs, + ): + super().__init__( + depth, + hidden_size, + hidden_act, + intermediate_size, + num_heads, + in_channels, + patch_size, + spatial_merge_size, + temporal_patch_size, + window_size, + out_hidden_size, + fullatt_block_indexes, + initializer_range=initializer_range, + **kwargs, + ) + del self.tokens_per_second + + +class Qwen2_5OmniAudioEncoderConfig(Qwen2AudioEncoderConfig): + r""" + This is the configuration class to store the configuration of a [`Qwen2_5OmniAudioEncoder`]. It is used to instantiate a + Qwen2.5-Omni-Thinker audio encoder according to the specified arguments, defining the model architecture. Instantiating a + configuration with the defaults will yield a similar configuration to that of the audio encoder of the Qwen2-Audio + architecture. + + e.g. [Qwen/Qwen2.5-Omni-7B](https://huggingface.co/Qwen/Qwen2.5-Omni-7B) + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + num_mel_bins (`int`, *optional*, defaults to 128): + Number of mel features used per input features. Should correspond to the value used in the + `Qwen2_5OmniProcessor` class. + encoder_layers (`int`, *optional*, defaults to 32): + Number of encoder layers. + encoder_attention_heads (`int`, *optional*, defaults to 20): + Number of attention heads for each attention layer in the Transformer encoder. + encoder_ffn_dim (`int`, *optional*, defaults to 5120): + Dimensionality of the "intermediate" (often named feed-forward) layer in encoder. + d_model (`int`, *optional*, defaults to 1280): + Dimensionality of the layers. + dropout (`float`, *optional*, defaults to 0.0): + The dropout probability for all fully connected layers in the embeddings, encoder, and pooler. + attention_dropout (`float`, *optional*, defaults to 0.0): + The dropout ratio for the attention probabilities. + activation_function (`str`, *optional*, defaults to `"gelu"`): + The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`, + `"relu"`, `"silu"` and `"gelu_new"` are supported. + activation_dropout (`float`, *optional*, defaults to 0.0): + The dropout ratio for activations inside the fully connected layer. + scale_embedding (`bool`, *optional*, defaults to `False`): + Scale embeddings by diving by sqrt(d_model). + initializer_range (`float`, *optional*, defaults to 0.02): + The standard deviation of the truncated_normal_initializer for initializing all weight matrices. + max_source_positions (`int`, *optional*, defaults to 1500): + The maximum sequence length of log-mel filter-bank features that this model might ever be used with. + n_window (`int`, *optional*, defaults to 100): + The chunk for conv and flash attn in AudioEncoder. + output_dim (`int`, *optional*, defaults to 3584): + The output dimension of AudioEncoder. + + Example: + + ```python + >>> from transformers import Qwen2_5OmniAudioEncoderConfig, Qwen2_5OmniAudioEncoder + + >>> # Initializing a Qwen2_5OmniAudioEncoderConfig + >>> configuration = Qwen2_5OmniAudioEncoderConfig() + + >>> # Initializing a Qwen2_5OmniAudioEncoder (with random weights) + >>> model = Qwen2_5OmniAudioEncoder(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "qwen2_5_omni_audio_encoder" + + def __init__( + self, + num_mel_bins=128, + encoder_layers=32, + encoder_attention_heads=20, + encoder_ffn_dim=5120, + d_model=1280, + dropout=0, + attention_dropout=0, + activation_function="gelu", + activation_dropout=0, + scale_embedding=False, + initializer_range=0.02, + max_source_positions=1500, + n_window=100, + output_dim=3584, + **kwargs, + ): + super().__init__( + num_mel_bins, + encoder_layers, + encoder_attention_heads, + encoder_ffn_dim, + d_model, + dropout, + attention_dropout, + activation_function, + activation_dropout, + scale_embedding, + initializer_range, + max_source_positions, + **kwargs, + ) + self.n_window = n_window + self.output_dim = output_dim + del self.encoder_layerdrop + + +class Qwen2_5OmniTextConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`Qwen2_5OmniThinkerForConditionalGeneration`]. It is used to instantiate an + Qwen2.5-Omni-Thinker model according to the specified arguments, defining the model architecture. Instantiating a configuration + with the defaults will yield a similar configuration to that of the Qwen2.5-Omni-Thinker. + + e.g. [Qwen/Qwen2.5-Omni-7B](https://huggingface.co/Qwen/Qwen2.5-Omni-7B) + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + vocab_size (`int`, *optional*, defaults to 152064): + Vocabulary size of the QwenOmni model. Defines the number of different tokens that can be represented by the + `inputs_ids` passed when calling [`Qwen2VLModel`] + hidden_size (`int`, *optional*, defaults to 3584): + Dimension of the hidden representations. + intermediate_size (`int`, *optional*, defaults to 18944): + Dimension of the MLP representations. + num_hidden_layers (`int`, *optional*, defaults to 28): + Number of hidden layers in the Transformer encoder. + num_attention_heads (`int`, *optional*, defaults to 28): + Number of attention heads for each attention layer in the Transformer encoder. + num_key_value_heads (`int`, *optional*, defaults to 4): + This is the number of key_value heads that should be used to implement Grouped Query Attention. If + `num_key_value_heads=num_attention_heads`, the model will use Multi Head Attention (MHA), if + `num_key_value_heads=1` the model will use Multi Query Attention (MQA) otherwise GQA is used. When + converting a multi-head checkpoint to a GQA checkpoint, each group key and value head should be constructed + by meanpooling all the original heads within that group. For more details, check out [this + paper](https://huggingface.co/papers/2305.13245). If it is not specified, will default to `32`. + hidden_act (`str` or `function`, *optional*, defaults to `"silu"`): + The non-linear activation function (function or string) in the decoder. + max_position_embeddings (`int`, *optional*, defaults to 32768): + The maximum sequence length that this model might ever be used with. + rms_norm_eps (`float`, *optional*, defaults to 1e-06): + The epsilon used by the rms normalization layers. + use_cache (`bool`, *optional*, defaults to `True`): + Whether or not the model should return the last key/values attentions (not used by all models). Only + relevant if `config.is_decoder=True`. + use_sliding_window (`bool`, *optional*, defaults to `False`): + Whether to use sliding window attention. + sliding_window (`int`, *optional*, defaults to 32768): + Sliding window attention (SWA) window size. If not specified, will default to `4096`. + max_window_layers (`int`, *optional*, defaults to 28): + The number of layers using full attention. The first `max_window_layers` layers will use full attention, while any + additional layer afterwards will use SWA (Sliding Window Attention). + layer_types (`list`, *optional*): + Attention pattern for each layer. + attention_dropout (`float`, *optional*, defaults to 0.0): + The dropout ratio for the attention probabilities. + rope_parameters (`RopeParameters`, *optional*): + Dictionary containing the configuration parameters for the RoPE embeddings. The dictionary should contain + a value for `rope_theta` and optionally parameters used for scaling in case you want to use RoPE + with longer `max_position_embeddings`. + initializer_range (`float`, *optional*, defaults to 0.02): + The standard deviation of the truncated_normal_initializer for initializing all weight matrices. + tie_word_embeddings (`bool`, *optional*, defaults to `True`): + Whether to tie weight embeddings + + Example: + + ```python + >>> from transformers import Qwen2_5OmniThinkerForConditionalGeneration, Qwen2_5OmniThinkerConfig, Qwen2_5OmniAudioEncoderConfig, Qwen2_5OmniVisionEncoderConfig + + >>> # Initializing a Qwen2_5OmniAudioEncoder config + >>> audio_config = Qwen2_5OmniAudioEncoderConfig() + + >>> # Initializing a Qwen2_5OmniVisionEncoder config + >>> vision_config = Qwen2_5OmniVisionEncoderConfig() + + >>> # Initializing a Qwen2.5OmniThinker configuration + >>> configuration = Qwen2_5OmniThinkerConfig(audio_config, vision_config) + + >>> # Initializing a model from the Qwen-Omni style configuration + >>> model = Qwen2_5OmniThinkerForConditionalGeneration(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "qwen2_5_omni_text" + keys_to_ignore_at_inference = ["past_key_values"] + default_theta = 1000000.0 + + # Default tensor parallel plan for base model `Qwen25OmniText` + base_model_tp_plan = { + "layers.*.self_attn.q_proj": "colwise", + "layers.*.self_attn.k_proj": "colwise", + "layers.*.self_attn.v_proj": "colwise", + "layers.*.self_attn.o_proj": "rowwise", + "layers.*.mlp.gate_proj": "colwise", + "layers.*.mlp.up_proj": "colwise", + "layers.*.mlp.down_proj": "rowwise", + } + base_model_pp_plan = { + "embed_tokens": (["input_ids"], ["inputs_embeds"]), + "layers": (["hidden_states", "attention_mask"], ["hidden_states"]), + "norm": (["hidden_states"], ["hidden_states"]), + } + + def __init__( + self, + vocab_size: int | None = 152064, + hidden_size: int | None = 3584, + intermediate_size: int | None = 18944, + num_hidden_layers: int | None = 28, + num_attention_heads: int | None = 28, + num_key_value_heads: int | None = 4, + hidden_act: str | None = "silu", + max_position_embeddings: int | None = 32768, + initializer_range: float | None = 0.02, + rms_norm_eps: int | None = 1e-6, + use_cache: bool | None = True, + rope_parameters: RopeParameters | dict[str, RopeParameters] | None = None, + use_sliding_window: bool | None = False, + sliding_window: int | None = 32768, + max_window_layers: int | None = 28, + layer_types: list[str] | None = None, + attention_dropout: float | None = 0.0, + pad_token_id: int | None = None, + bos_token_id: int | None = None, + eos_token_id: int | None = None, + tie_word_embeddings: bool | None = True, + **kwargs, + ): + self.vocab_size = vocab_size + self.max_position_embeddings = max_position_embeddings + self.hidden_size = hidden_size + self.intermediate_size = intermediate_size + self.num_hidden_layers = num_hidden_layers + self.num_attention_heads = num_attention_heads + self.use_sliding_window = use_sliding_window + self.sliding_window = sliding_window if self.use_sliding_window else None + self.max_window_layers = max_window_layers + self.pad_token_id = pad_token_id + self.bos_token_id = bos_token_id + self.eos_token_id = eos_token_id + self.tie_word_embeddings = tie_word_embeddings + + # for backward compatibility + if num_key_value_heads is None: + num_key_value_heads = num_attention_heads + + self.num_key_value_heads = num_key_value_heads + self.hidden_act = hidden_act + self.initializer_range = initializer_range + self.rms_norm_eps = rms_norm_eps + self.use_cache = use_cache + self.attention_dropout = attention_dropout + + self.layer_types = layer_types + if self.layer_types is None: + self.layer_types = [ + "sliding_attention" + if self.sliding_window is not None and i >= self.max_window_layers + else "full_attention" + for i in range(self.num_hidden_layers) + ] + layer_type_validation(self.layer_types, self.num_hidden_layers) + + self.rope_parameters = rope_parameters + super().__init__( + ignore_keys_at_rope_validation={"mrope_section"}, + **kwargs, + ) + + +class Qwen2_5OmniThinkerConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`Qwen2_5OmniThinkerForConditionalGeneration`]. It is used to instantiate an + Qwen2.5-Omni-Thinker model according to the specified arguments, defining the model architecture. Instantiating a configuration + with the defaults will yield a similar configuration to that of the Qwen2.5-Omni-Thinker. + + e.g. [Qwen/Qwen2.5-Omni-7B](https://huggingface.co/Qwen/Qwen2.5-Omni-7B) + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + audio_config (`dict`, *optional*): + The config dictionary of the audio backbone. + vision_config (`dict`, *optional*): + The config dictionary of the vision backbone. + text_config (`dict`, *optional*): + The config dictionary of the text backbone. + audio_token_index (`int`, *optional*, defaults to 151646): + The audio token index to encode the audio prompt. + image_token_index (`int`, *optional*, defaults to 151655): + The image token index to encode the image prompt. + video_token_index (`int`, *optional*, defaults to 151656): + The video token index to encode the video prompt. + position_id_per_seconds (`int`, *optional*, defaults to 25): + The increment of position id per second. + seconds_per_chunk (`int`, *optional*, defaults to 2): + The duration in seconds of the chunk of audio and video data. + audio_start_token_id (`int`, *optional*, defaults to 151647): + The audio start token index to encode the audio prompt. + audio_end_token_id (`int`, *optional*, defaults to 151648): + The audio end token index to encode the audio prompt. + user_token_id (`int, *optional*, defaults to 872): + The user token index to encode the user token. + initializer_range (`float`, *optional*, defaults to 0.02): + The standard deviation of the truncated_normal_initializer for initializing all weight matrices. + tie_word_embeddings (`bool`, *optional*, defaults to `False`): + Whether the model's input and output word embeddings should be tied. + + Example: + + ```python + >>> from transformers import Qwen2_5OmniThinkerForConditionalGeneration, Qwen2_5OmniThinkerConfig, Qwen2_5OmniAudioEncoderConfig, Qwen2_5OmniVisionEncoderConfig + + >>> # Initializing a Qwen2_5OmniAudioEncoder config + >>> audio_config = Qwen2_5OmniAudioEncoderConfig() + + >>> # Initializing a Qwen2_5OmniVisionEncoder config + >>> vision_config = Qwen2_5OmniVisionEncoderConfig() + + >>> # Initializing a Qwen2_5OmniTextConfig config + >>> text_config = Qwen2_5OmniTextConfig() + + >>> # Initializing a Qwen2.5OmniThinker configuration + >>> configuration = Qwen2_5OmniThinkerConfig(audio_config, vision_config, text_config) + + >>> # Initializing a model from the Qwen-Omni style configuration + >>> model = Qwen2_5OmniThinkerForConditionalGeneration(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "qwen2_5_omni_thinker" + attribute_map = { + "image_token_id": "image_token_index", + "video_token_id": "video_token_index", + "audio_token_id": "audio_token_index", + } + sub_configs = { + "audio_config": Qwen2_5OmniAudioEncoderConfig, + "vision_config": Qwen2_5OmniVisionEncoderConfig, + "text_config": Qwen2_5OmniTextConfig, + } + + def __init__( + self, + audio_config=None, + vision_config=None, + text_config=None, + audio_token_index=151646, + image_token_index=151655, + video_token_index=151656, + position_id_per_seconds=25, + seconds_per_chunk=2, + audio_start_token_id=151647, + audio_end_token_id=151648, + user_token_id=872, + initializer_range=0.02, + tie_word_embeddings=False, + **kwargs, + ): + self.audio_token_index = audio_token_index + self.image_token_index = image_token_index + self.video_token_index = video_token_index + self.user_token_id = user_token_id + self.position_id_per_seconds = position_id_per_seconds + self.seconds_per_chunk = seconds_per_chunk + self.audio_start_token_id = audio_start_token_id + self.audio_end_token_id = audio_end_token_id + self.initializer_range = initializer_range + self.tie_word_embeddings = tie_word_embeddings + + if isinstance(vision_config, dict): + vision_config = Qwen2_5OmniVisionEncoderConfig(**vision_config) + elif vision_config is None: + vision_config = Qwen2_5OmniVisionEncoderConfig() + self.vision_config = vision_config + + if isinstance(audio_config, dict): + audio_config = Qwen2_5OmniAudioEncoderConfig(**audio_config) + elif audio_config is None: + audio_config = Qwen2_5OmniAudioEncoderConfig() + self.audio_config = audio_config + + if isinstance(text_config, dict): + text_config = Qwen2_5OmniTextConfig(**text_config) + elif text_config is None: + text_config = Qwen2_5OmniTextConfig() + self.text_config = text_config + + super().__init__(**kwargs) + + +class Qwen2_5OmniTalkerConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`Qwen2_5OmniTalkerForConditionalGeneration`]. It is used to instantiate an + Qwen2.5-Omni-Talker model according to the specified arguments, defining the model architecture. Instantiating a configuration + with the defaults will yield a similar configuration to that of the Qwen2.5-Omni-Thinker. + + e.g. [Qwen/Qwen2.5-Omni-7B](https://huggingface.co/Qwen/Qwen2.5-Omni-7B) + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + audio_token_index (`int`, *optional*, defaults to 151646): + The audio token index to encode the audio prompt. + image_token_index (`int`, *optional*, defaults to 151655): + The image token index to encode the image prompt. + video_token_index (`int`, *optional*, defaults to 151656): + The video token index to encode the video prompt. + vocab_size (`int`, *optional*, defaults to 8448): + Vocabulary size of the QwenOmni model. Defines the number of different tokens that can be represented by the + `inputs_ids` passed when calling [`Qwen2VLModel`] + tts_text_start_token_id (`int`, *optional*, defaults to 151860): + The tts text start token index to encode the start of tts text. + tts_text_end_token_id (`int`, *optional*, defaults to 151861): + The tts text end token index to encode the end of tts text. + tts_text_pad_token_id (`int`, *optional*, defaults to 151859): + The tts text pad token index to encode the pad of tts text. + tts_codec_start_token_id (`int`, *optional*, defaults to 8293): + The tts codec start token index to encode the start of tts codec. + tts_codec_end_token_id (`int`, *optional*, defaults to 8294): + The tts codec end token index to encode the end of tts codec. + tts_codec_pad_token_id (`int`, *optional*, defaults to 8292): + The tts codec pad token index to encode the pad of tts codec. + tts_codec_mask_token_id (`int`, *optional*, defaults to 8296): + The tts codec mask token index to encode the mask of tts codec. + vision_start_token_id (`int`, *optional*, defaults to 151652): + The tts vision start token index to encode the start of vision. + vision_end_token_id (`int`, *optional*, defaults to 151653): + The tts vision end token index to encode the end of vision. + embedding_size (`int`, *optional*, defaults to 3584): + Dimension of the embedding representations. + hidden_size (`int`, *optional*, defaults to 3584): + Dimension of the hidden representations. + intermediate_size (`int`, *optional*, defaults to 18944): + Dimension of the MLP representations. + num_hidden_layers (`int`, *optional*, defaults to 28): + Number of hidden layers in the Transformer encoder. + num_attention_heads (`int`, *optional*, defaults to 28): + Number of attention heads for each attention layer in the Transformer encoder. + num_key_value_heads (`int`, *optional*, defaults to 4): + This is the number of key_value heads that should be used to implement Grouped Query Attention. If + `num_key_value_heads=num_attention_heads`, the model will use Multi Head Attention (MHA), if + `num_key_value_heads=1` the model will use Multi Query Attention (MQA) otherwise GQA is used. When + converting a multi-head checkpoint to a GQA checkpoint, each group key and value head should be constructed + by meanpooling all the original heads within that group. For more details, check out [this + paper](https://huggingface.co/papers/2305.13245). If it is not specified, will default to `32`. + hidden_act (`str` or `function`, *optional*, defaults to `"silu"`): + The non-linear activation function (function or string) in the decoder. + max_position_embeddings (`int`, *optional*, defaults to 32768): + The maximum sequence length that this model might ever be used with. + rms_norm_eps (`float`, *optional*, defaults to 1e-06): + The epsilon used by the rms normalization layers. + head_dim (`int`, *optional*, defaults to 128): + The dimension of each attention head. + use_cache (`bool`, *optional*, defaults to `True`): + Whether or not the model should return the last key/values attentions (not used by all models). Only + relevant if `config.is_decoder=True`. + tie_word_embeddings (`bool`, *optional*, defaults to `False`): + Whether the model's input and output word embeddings should be tied. + use_sliding_window (`bool`, *optional*, defaults to `False`): + Whether to use sliding window attention. + sliding_window (`int`, *optional*, defaults to 32768): + Sliding window attention (SWA) window size. If not specified, will default to `4096`. + max_window_layers (`int`, *optional*, defaults to 28): + The number of layers using full attention. The first `max_window_layers` layers will use full attention, while any + additional layer afterwards will use SWA (Sliding Window Attention). + attention_dropout (`float`, *optional*, defaults to 0.0): + The dropout ratio for the attention probabilities. + rope_parameters (`RopeParameters`, *optional*): + Dictionary containing the configuration parameters for the RoPE embeddings. The dictionary should contain + a value for `rope_theta` and optionally parameters used for scaling in case you want to use RoPE + with longer `max_position_embeddings`. + position_id_per_seconds (`int`, *optional*, defaults to 25): + The increment of position id per second. + seconds_per_chunk (`int`, *optional*, defaults to 2): + The duration in seconds of the chunk of audio and video data. + audio_start_token_id (`int`, *optional*, defaults to 151647): + The audio start token index to encode the audio prompt. + audio_end_token_id (`int`, *optional*, defaults to 151648): + The audio end token index to encode the audio prompt. + initializer_range (`float`, *optional*, defaults to 0.02): + The standard deviation of the truncated_normal_initializer for initializing all weight matrices. + spatial_merge_size (`int`, *optional*, defaults to 2): + The size used for merging spatial dimensions. + layer_types (`list`, *optional*): + Attention pattern for each layer. + pad_token_id (`int`, *optional*): + The id of the padding token. + + + Example: + + ```python + >>> from transformers import Qwen2_5OmniTalkerForConditionalGeneration, Qwen2_5OmniThinkerConfig, Qwen2_5OmniAudioEncoderConfig, Qwen2_5OmniVisionEncoderConfig + + >>> # Initializing a Qwen2_5OmniAudioEncoder config + >>> audio_config = Qwen2_5OmniAudioEncoderConfig() + + >>> # Initializing a Qwen2 config + >>> text_config = Qwen2Config() + + >>> # Initializing a Qwen2_5Omni configuration + >>> configuration = Qwen2_5OmniThinkerConfig(audio_config, text_config) + + >>> # Initializing a model from the qwen2-audio style configuration + >>> model = Qwen2_5OmniTalkerForConditionalGeneration(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "qwen2_5_omni_talker" + default_theta = 1000000.0 + attribute_map = { + "image_token_id": "image_token_index", + "video_token_id": "video_token_index", + "audio_token_id": "audio_token_index", + } + + def __init__( + self, + audio_token_index=151646, + image_token_index=151655, + video_token_index=151656, + vocab_size=8448, + tts_text_start_token_id=151860, + tts_text_end_token_id=151861, + tts_text_pad_token_id=151859, + tts_codec_start_token_id=8293, + tts_codec_end_token_id=8294, + tts_codec_pad_token_id=8292, + tts_codec_mask_token_id=8296, + vision_start_token_id=151652, + vision_end_token_id=151653, + embedding_size=3584, + hidden_size=3584, + intermediate_size=18944, + num_hidden_layers=28, + num_attention_heads=28, + num_key_value_heads=4, + hidden_act="silu", + max_position_embeddings=32768, + rms_norm_eps=1e-06, + head_dim=128, + use_cache=True, + tie_word_embeddings=False, + use_sliding_window=False, + sliding_window=32768, + max_window_layers=28, + attention_dropout=0.0, + rope_parameters: RopeParameters | dict[str, RopeParameters] | None = None, + position_id_per_seconds=25, + seconds_per_chunk=2, + audio_start_token_id=151647, + audio_end_token_id=151648, + initializer_range=0.02, + spatial_merge_size=2, + layer_types=None, + pad_token_id: int | None = None, + **kwargs, + ): + self.audio_token_index = audio_token_index + self.image_token_index = image_token_index + self.video_token_index = video_token_index + + self.tts_text_start_token_id = tts_text_start_token_id + self.tts_text_end_token_id = tts_text_end_token_id + self.tts_text_pad_token_id = tts_text_pad_token_id + self.tts_codec_start_token_id = tts_codec_start_token_id + self.tts_codec_end_token_id = tts_codec_end_token_id + self.tts_codec_pad_token_id = tts_codec_pad_token_id + + self.tts_codec_mask_token_id = tts_codec_mask_token_id + + self.vision_start_token_id = vision_start_token_id + self.vision_end_token_id = vision_end_token_id + + self.vocab_size = vocab_size + self.head_dim = head_dim + self.embedding_size = embedding_size + self.max_position_embeddings = max_position_embeddings + self.hidden_size = hidden_size + self.intermediate_size = intermediate_size + self.num_hidden_layers = num_hidden_layers + self.num_attention_heads = num_attention_heads + self.use_sliding_window = use_sliding_window + self.sliding_window = sliding_window if self.use_sliding_window else None + self.max_window_layers = max_window_layers + + # for backward compatibility + if num_key_value_heads is None: + num_key_value_heads = num_attention_heads + + self.num_key_value_heads = num_key_value_heads + self.hidden_act = hidden_act + self.rms_norm_eps = rms_norm_eps + self.use_cache = use_cache + self.attention_dropout = attention_dropout + self.position_id_per_seconds = position_id_per_seconds # zf + self.seconds_per_chunk = seconds_per_chunk # zf + self.audio_start_token_id = audio_start_token_id # zf + self.audio_end_token_id = audio_end_token_id # zf + self.pad_token_id = pad_token_id + + self.initializer_range = initializer_range + self.spatial_merge_size = spatial_merge_size + self.tie_word_embeddings = tie_word_embeddings + + self.layer_types = layer_types + if self.layer_types is None: + self.layer_types = [ + "sliding_attention" + if self.sliding_window is not None and i >= self.max_window_layers + else "full_attention" + for i in range(self.num_hidden_layers) + ] + layer_type_validation(self.layer_types, self.num_hidden_layers) + + self.rope_parameters = rope_parameters + super().__init__(ignore_keys_at_rope_validation={"mrope_section"}, **kwargs) + + +class Qwen2_5OmniDiTConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of the Qwen2_5OmniToken2WavDiT used in the Qwen2.5-Omni-Token2Wav model. + It defines the architecture of the DiT model, which is used for generating mel-spectrograms from tokens. + + Args: + hidden_size (`int`, *optional*, defaults to 1024): + The dimension of the model. + num_hidden_layers (`int`, *optional*, defaults to 22): + The number of transformer blocks in the DiT model. + num_attention_heads (`int`, *optional*, defaults to 16): + The number of attention heads in each transformer block. + ff_mult (`int`, *optional*, defaults to 2): + The multiplier for the feedforward layer in each transformer block. + emb_dim (`int`, *optional*, defaults to 512): + The dimension of the embedding layer. + head_dim (`int`, *optional*, defaults to 64): + The dimension of each attention head. + repeats (`int`, *optional*, defaults to 2): + The number of times the codec embeddings are repeated. + num_embeds (`int`, *optional*, defaults to 8193): + The number of unique embeddings in the codec. + mel_dim (`int`, *optional*, defaults to 80): + The dimension of the mel-spectrogram. + dropout (`float`, *optional*, defaults to 0.1): + The dropout rate for the transformer blocks. + + enc_emb_dim (`int`, *optional*, defaults to 192): + The dimension of the pre-trained speaker embedding. + enc_dim (`int`, *optional*, defaults to 128): + The dimension of the encoder output. + enc_channels (`list[int]`, *optional*, defaults to `[256, 256, 256, 256, 768]`): + A list of output channels for each TDNN/SERes2Net layer in the encoder. + enc_kernel_sizes (`list[int]`, *optional*, defaults to `[5, 3, 3, 3, 1]`): + A list of kernel sizes for each layer in the encoder. + enc_dilations (`list[int]`, *optional*, defaults to `[1, 2, 3, 4, 1]`): + A list of dilations for each layer in the encoder. + enc_attention_channels (`int`, *optional*, defaults to 64): + The number of attention channels in the SqueezeExcitationBlock. + enc_res2net_scale (`int`, *optional*, defaults to 2): + The scale of the Res2Net block in the encoder. + enc_se_channels (`int`, *optional*, defaults to 64): + The number of output channels after squeeze in the SqueezeExcitationBlock. + """ + + model_type = "qwen2_5_omni_dit" + + def __init__( + self, + hidden_size=1024, + num_hidden_layers=22, + num_attention_heads=16, + ff_mult=2, + emb_dim=512, + head_dim=64, + rope_parameters: RopeParameters | dict[str, RopeParameters] | None = None, + max_position_embeddings=32768, + block_size=24, + look_ahead_layers=[10], + look_backward_layers=[0, 20], + repeats=2, + num_embeds=8193, + mel_dim=80, + dropout=0.1, + enc_emb_dim=192, + enc_dim=128, + enc_channels=[256, 256, 256, 256, 768], + enc_kernel_sizes=[5, 3, 3, 3, 1], + enc_dilations=[1, 2, 3, 4, 1], + enc_attention_channels=64, + enc_res2net_scale=2, + enc_se_channels=64, + **kwargs, + ): + self.hidden_size = hidden_size + self.num_hidden_layers = num_hidden_layers + self.num_attention_heads = num_attention_heads + self.ff_mult = ff_mult + self.emb_dim = emb_dim + self.head_dim = head_dim + self.max_position_embeddings = max_position_embeddings + self.block_size = block_size + self.look_ahead_layers = look_ahead_layers + self.look_backward_layers = look_backward_layers + self.repeats = repeats + self.num_embeds = num_embeds + self.mel_dim = mel_dim + self.dropout = dropout + self.enc_emb_dim = enc_emb_dim + self.enc_dim = enc_dim + self.enc_channels = enc_channels + self.enc_kernel_sizes = enc_kernel_sizes + self.enc_dilations = enc_dilations + self.enc_attention_channels = enc_attention_channels + self.enc_res2net_scale = enc_res2net_scale + self.enc_se_channels = enc_se_channels + self.rope_parameters = rope_parameters + + super().__init__(**kwargs) + + +class Qwen2_5OmniBigVGANConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of the Qwen2_5OmniToken2WavBigVGAN module used in the Qwen2.5-Omni-Token2Wav model. + It defines the architecture of the BigVGAN model, which is used for converting mel-spectrograms to waveforms. + + Args: + mel_dim (`int`, *optional*, defaults to 80): + The dimension of the mel-spectrogram. + upsample_initial_channel (`int`, *optional*, defaults to 1536): + The number of channels in the initial upsampling layer. + resblock_kernel_sizes (`list[int]`, *optional*, defaults to `[3, 7, 11]`): + A list of kernel sizes for each residual block. + resblock_dilation_sizes (`list[list[int]]`, *optional*, defaults to `[[1, 3, 5], [1, 3, 5], [1, 3, 5]]`): + A list of dilation sizes for each residual block. + upsample_rates (`list[int]`, *optional*, defaults to `[5, 3, 2, 2, 2, 2]`): + A list of upsampling rates for each upsampling layer. + upsample_kernel_sizes (`list[int]`, *optional*, defaults to `[11, 7, 4, 4, 4, 4]`): + A list of kernel sizes for each upsampling layer. + """ + + model_type = "qwen2_5_omni_bigvgan" + + def __init__( + self, + mel_dim=80, + upsample_initial_channel=1536, + resblock_kernel_sizes=[3, 7, 11], + resblock_dilation_sizes=[[1, 3, 5], [1, 3, 5], [1, 3, 5]], + upsample_rates=[5, 3, 2, 2, 2, 2], + upsample_kernel_sizes=[11, 7, 4, 4, 4, 4], + **kwargs, + ): + self.mel_dim = mel_dim + self.upsample_initial_channel = upsample_initial_channel + self.resblock_kernel_sizes = resblock_kernel_sizes + self.resblock_dilation_sizes = resblock_dilation_sizes + self.upsample_rates = upsample_rates + self.upsample_kernel_sizes = upsample_kernel_sizes + super().__init__(**kwargs) + + +class Qwen2_5OmniToken2WavConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`Qwen2_5OmniToken2WavModel`]. + It is used to instantiate the Qwen2.5-Omni-Token2Wav model which combines a Diffusion Transformer (DiT) for mel-spectrogram generation with a BigVGAN model for waveform synthesis. The configuration contains sub-configurations for both components. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + dit_config ([`DiT_Args`], *optional*): + Configuration class for the Diffusion Transformer (DiT) module responsible for generating mel-spectrograms. + bigvgan_config ([`BigVGAN_Args`], *optional*): + Configuration class for the BigVGAN module responsible for converting mel-spectrograms to waveforms. + Example: + + ```python + >>> from transformers import Qwen2_5OmniToken2WavModel, DiT_Args, BigVGAN_Args + + >>> # Initialize DiT configuration + >>> dit_config = DiT_Args( + ... dim=1024, + ... depth=22, + ... heads=16, + ... ff_mult=2 + ... ) + + >>> # Initialize BigVGAN configuration + >>> bigvgan_config = BigVGAN_Args( + ... mel_dim=80, + ... upsample_rates=[5,3,2,2,2,2] + ... ) + + >>> # Initialize main configuration + >>> config = Qwen2_5OmniToken2WavConfig(dit_config, bigvgan_config) + + >>> # Initialize model with config + >>> model = Qwen2_5OmniToken2Wav(config) + + >>> # Accessing the model configuration + >>> configuration = model.config + ``` + """ + + model_type = "qwen2_5_omni_token2wav" + sub_configs = { + "dit_config": Qwen2_5OmniDiTConfig, + "bigvgan_config": Qwen2_5OmniBigVGANConfig, + } + + def __init__(self, dit_config=None, bigvgan_config=None, **kwargs): + if dit_config is None: + dit_config = {} + if bigvgan_config is None: + bigvgan_config = {} + self.dit_config = Qwen2_5OmniDiTConfig(**dit_config) + self.bigvgan_config = Qwen2_5OmniBigVGANConfig(**bigvgan_config) + super().__init__(**kwargs) + + +class Qwen2_5OmniConfig(PreTrainedConfig): + """ + This is the configuration class to store the configuration of a [`Qwen2_5OmniForConditionalGeneration`]. It is used to instantiate a Qwen2.5Omni + model according to the specified sub-models configurations, defining the model architecture. + + Instantiating a configuration with the defaults will yield a similar configuration to that of the + [Qwen/Qwen2.5-Omni-7B](https://huggingface.co/Qwen/Qwen2.5-Omni-7B) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + thinker_config (`dict`, *optional*): Configuration of the underlying thinker sub-model. + talker_config (`dict`, *optional*): Configuration of the underlying talker sub-model. + token2wav_config (`dict`, *optional*): Configuration of the underlying codec sub-model. + enable_audio_output (`bool`, *optional*, defaults to `True`): Whether enable audio output and load talker and token2wav module. + + Example: + + ```python + >>> from transformers import ( + ... Qwen2_5OmniThinkerConfig, + ... Qwen2_5OmniTalkerConfig, + ... Qwen2_5OmniToken2WavConfig, + ... Qwen2_5OmniForConditionalGeneration, + ... Qwen2_5OmniConfig, + ... ) + + >>> # Initializing sub-modules configurations. + >>> thinker_config = Qwen2_5OmniThinkerConfig() + >>> talker_config = Qwen2_5OmniTalkerConfig() + >>> token2wav_config = Qwen2_5OmniToken2WavConfig() + + + >>> # Initializing a module style configuration + >>> configuration = Qwen2_5OmniConfig( + ... thinker_config, talker_config, token2wav_config + ... ) + + >>> # Initializing a model (with random weights) + >>> model = Qwen2_5OmniForConditionalGeneration(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ``` + """ + + model_type = "qwen2_5_omni" + sub_configs = { + "thinker_config": Qwen2_5OmniThinkerConfig, + "talker_config": Qwen2_5OmniTalkerConfig, + "token2wav_config": Qwen2_5OmniToken2WavConfig, + } + + def __init__( + self, + thinker_config=None, + talker_config=None, + token2wav_config=None, + enable_audio_output: bool = True, + **kwargs, + ): + if thinker_config is None: + thinker_config = {} + logger.info("thinker_config is None. Initializing thinker model with default values") + + if talker_config is None: + talker_config = {} + logger.info("talker_config is None. Initializing talker model with default values") + + if token2wav_config is None: + token2wav_config = {} + logger.info("token2wav_config is None. Initializing token2wav model with default values") + + self.thinker_config = Qwen2_5OmniThinkerConfig(**thinker_config) + self.talker_config = Qwen2_5OmniTalkerConfig(**talker_config) + self.token2wav_config = Qwen2_5OmniToken2WavConfig(**token2wav_config) + self.enable_audio_output = enable_audio_output + + super().__init__(**kwargs) + + def get_text_config(self, *args, **kwargs): + """ + Returns the config that is meant to be used with text IO. On most models, it is the original config instance + itself. On specific composite models, it is under a set of valid names. + + Args: + decoder (`Optional[bool]`, *optional*, defaults to `False`): + If set to `True`, then only search for decoder config names. + """ + # Overridden for deeply nested config like Qwen2-Omni. We don't have any omni model + # except for Qwen yet. This has to be generalized if more deeply nested configs are + # added. NOTE: currently method used only by vLLM + return self.thinker_config.get_text_config(*args, **kwargs) + + +class Qwen2_5OmniPreTrainedModel(Qwen2_5_VLPreTrainedModel): + config: Qwen2_5OmniConfig + input_modalities = ("image", "video", "audio", "text") + _can_compile_fullgraph = False + + def _init_weights(self, module): + PreTrainedModel._init_weights(self, module) + if isinstance(module, SinusoidsPositionEmbedding): + log_timescale_increment = np.log(module.max_timescale) / (module.channels // 2 - 1) + inv_timescales = torch.exp(-log_timescale_increment * torch.arange(module.channels // 2).float()) + scaled_time = torch.arange(module.length)[:, np.newaxis] * inv_timescales[np.newaxis, :] + init.copy_(module.positional_embedding, torch.cat([torch.sin(scaled_time), torch.cos(scaled_time)], dim=1)) + elif isinstance(module, UpSample1d): + filter_tensor = kaiser_sinc_filter1d(0.5 / module.ratio, 0.6 / module.ratio, module.kernel_size) + init.copy_(module.filter, filter_tensor) + elif isinstance(module, DownSample1d): + filter_tensor = kaiser_sinc_filter1d(module.cutoff, module.half_width, module.kernel_size) + init.copy_(module.filter, filter_tensor) + elif isinstance(module, Qwen2_5_VisionRotaryEmbedding): + inv_freq = 1.0 / (module.theta ** (torch.arange(0, module.dim, 2, dtype=torch.float) / module.dim)) + init.copy_(module.inv_freq, inv_freq) + + +class Qwen2_5OmniPreTrainedModelForConditionalGeneration(Qwen2_5OmniPreTrainedModel): + input_modalities = ("image", "video", "audio", "text") + + def get_llm_pos_ids_for_vision( + self, + start_idx: int, + vision_idx: int, + spatial_merge_size: int, + t_index: list[int], + grid_hs: list[int], + grid_ws: list[int], + ): + llm_pos_ids_list = [] + llm_grid_h = grid_hs[vision_idx] // spatial_merge_size + llm_grid_w = grid_ws[vision_idx] // spatial_merge_size + h_index = torch.arange(llm_grid_h).view(1, -1, 1).expand(len(t_index), -1, llm_grid_w).flatten() + w_index = torch.arange(llm_grid_w).view(1, 1, -1).expand(len(t_index), llm_grid_h, -1).flatten() + t_index = torch.Tensor(t_index).view(-1, 1).expand(-1, llm_grid_h * llm_grid_w).flatten().long() + _llm_pos_ids = torch.stack([t_index, h_index, w_index]) + llm_pos_ids_list.append(_llm_pos_ids + start_idx) # + 1 ) # 12.09 by malinhan + llm_pos_ids = torch.cat(llm_pos_ids_list, dim=1) + return llm_pos_ids + + def get_chunked_index( + self, token_indices: torch.Tensor, tokens_per_chunk: int, remove_index: int + ) -> list[tuple[int, int]]: + """ + Splits token index list into chunks based on token value ranges. + + Given a list of token indices, returns a list of (start, end) index tuples representing + slices of the list where the token values fall within successive ranges of `t_ntoken_per_chunk`. + + For example, if `t_ntoken_per_chunk` is 1000, the function will create chunks such that: + - the first chunk contains token values < 1000, + - the second chunk contains values >= 1000 and < 2000, and so on. + + Parameters: + token_indices (`torch.Tensor` of shape `(seq_len, )`): A monotonically increasing list of + token index values. + t_ntoken_per_chunk (`int`): Number of tokens per chunk (used as the chunk size threshold). + remove_index (`int`) An index id to subtract from `token_indices` before chunking + + Returns: + `list[tuple[int, int]]`: A list of tuples, each representing the start (inclusive) + and end (exclusive) indices of a chunk in `token_indices`. + """ + + def _iter(): + i, start_idx = 0, 0 # skip bos token + current_chunk = 1 + while i < len(token_indices): # skip eos token + if token_indices[i] - remove_index >= current_chunk * tokens_per_chunk: + yield (start_idx, i) + start_idx = i + current_chunk += 1 + i += 1 + yield (start_idx, len(token_indices)) + + return list(_iter()) + + def get_rope_index( + self, + input_ids: torch.LongTensor | None = None, + image_grid_thw: torch.LongTensor | None = None, + video_grid_thw: torch.LongTensor | None = None, + attention_mask: torch.Tensor | None = None, + use_audio_in_video: bool = False, + audio_seqlens: torch.LongTensor | None = None, + second_per_grids: torch.Tensor | None = None, + ) -> tuple[torch.Tensor, torch.Tensor]: + """ + Calculate the 3D rope index based on image and video's temporal, height and width in LLM. + + Explanation: + Each embedding sequence contains vision embedding and text embedding or just contains text embedding. + + For pure text embedding sequence, the rotary position embedding has no difference with modern LLMs. + Examples: + input_ids: [T T T T T], here T is for text. + temporal position_ids: [0, 1, 2, 3, 4] + height position_ids: [0, 1, 2, 3, 4] + width position_ids: [0, 1, 2, 3, 4] + + For vision and text embedding sequence, we calculate 3D rotary position embedding for vision part + and 1D rotary position embedding for text part. + Examples: + Temporal (Time): 3 patches, representing different segments of the video in time. + Height: 2 patches, dividing each frame vertically. + Width: 2 patches, dividing each frame horizontally. + We also have some important parameters: + fps (Frames Per Second): The video's frame rate, set to 1. This means one frame is processed each second. + tokens_per_second: This is a crucial parameter. It dictates how many "time-steps" or "temporal tokens" are conceptually packed into a one-second interval of the video. In this case, we have 25 tokens per second. So each second of the video will be represented with 25 separate time points. It essentially defines the temporal granularity. + temporal_patch_size: The number of frames that compose one temporal patch. Here, it's 2 frames. + interval: The step size for the temporal position IDs, calculated as tokens_per_second * temporal_patch_size / fps. In this case, 25 * 2 / 1 = 50. This means that each temporal patch will be have a difference of 50 in the temporal position IDs. + input_ids: [V V V V V V V V V V V V T T T T T], here V is for vision. + vision temporal position_ids: [0, 0, 0, 0, 50, 50, 50, 50, 100, 100, 100, 100] + vision height position_ids: [0, 0, 1, 1, 0, 0, 1, 1, 0, 0, 1, 1] + vision width position_ids: [0, 1, 0, 1, 0, 1, 0, 1, 0, 1, 0, 1] + text temporal position_ids: [101, 102, 103, 104, 105] + text height position_ids: [101, 102, 103, 104, 105] + text width position_ids: [101, 102, 103, 104, 105] + Here we calculate the text start position_ids as the max vision position_ids plus 1. + + Args: + input_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`): + Indices of input sequence tokens in the vocabulary. Padding will be ignored by default should you provide + it. + image_grid_thw (`torch.LongTensor` of shape `(num_images, 3)`, *optional*): + The temporal, height and width of feature shape of each image in LLM. + video_grid_thw (`torch.LongTensor` of shape `(num_videos, 3)`, *optional*): + The temporal, height and width of feature shape of each video in LLM. + attention_mask (`torch.Tensor` of shape `(batch_size, sequence_length)`, *optional*): + Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`: + + - 1 for tokens that are **not masked**, + - 0 for tokens that are **masked**. + use_audio_in_video (`bool`, *optional*): + If set to `True`, use the audio in video. + audio_seqlens (`torch.LongTensor` of shape `(num_audios)`, *optional*): + The length of feature shape of each audio in LLM. + second_per_grids (`torch.LongTensor` of shape `(num_videos)`, *optional*): + The time interval (in seconds) for each grid along the temporal dimension in the 3D position IDs. + + Returns: + position_ids (`torch.LongTensor` of shape `(3, batch_size, sequence_length)`) + mrope_position_deltas (`torch.Tensor` of shape `(batch_size)`) + """ + spatial_merge_size = self.spatial_merge_size + image_token_id = self.config.image_token_id + video_token_id = self.config.video_token_id + audio_token_id = self.config.audio_token_id + vision_start_token_id = self.config.vision_start_token_id + audio_start_token_id = self.config.audio_start_token_id + position_id_per_seconds = self.config.position_id_per_seconds + seconds_per_chunk = self.config.seconds_per_chunk + + mrope_position_deltas = [] + if input_ids is not None and (image_grid_thw is not None or video_grid_thw is not None): + total_input_ids = input_ids + if attention_mask is not None: + attention_mask = attention_mask == 1 + position_ids = torch.ones( + 3, + input_ids.shape[0], + input_ids.shape[1], + dtype=input_ids.dtype, + device=input_ids.device, + ) + image_idx, video_idx, audio_idx = 0, 0, 0 + for i, input_ids in enumerate(total_input_ids): + if attention_mask is not None: + input_ids = input_ids[attention_mask[i]] + image_nums, video_nums, audio_nums = 0, 0, 0 + vision_start_indices = torch.argwhere(input_ids == vision_start_token_id).squeeze(1) + vision_tokens = input_ids[vision_start_indices + 1] + audio_nums = torch.sum(input_ids == audio_start_token_id) + image_nums = (vision_tokens == image_token_id).sum() + video_nums = ( + (vision_tokens == audio_start_token_id).sum() + if use_audio_in_video + else (vision_tokens == video_token_id).sum() + ) + input_tokens = input_ids.tolist() + llm_pos_ids_list: list = [] + st = 0 + remain_images, remain_videos, remain_audios = image_nums, video_nums, audio_nums + multimodal_nums = ( + image_nums + audio_nums if use_audio_in_video else image_nums + video_nums + audio_nums + ) + for _ in range(multimodal_nums): + st_idx = llm_pos_ids_list[-1].max() + 1 if len(llm_pos_ids_list) > 0 else 0 + if image_token_id in input_tokens and remain_images > 0: + ed_image = input_tokens.index(image_token_id, st) + else: + ed_image = len(input_tokens) + 1 + if video_token_id in input_tokens and remain_videos > 0: + ed_video = input_tokens.index(video_token_id, st) + else: + ed_video = len(input_tokens) + 1 + if audio_token_id in input_tokens and remain_audios > 0: + ed_audio = input_tokens.index(audio_token_id, st) + else: + ed_audio = len(input_tokens) + 1 + min_ed = min(ed_image, ed_video, ed_audio) + if min_ed == ed_audio: + text_len = min_ed - st - 1 + if text_len != 0: + st_idx = llm_pos_ids_list[-1].max() + 1 if len(llm_pos_ids_list) > 0 else 0 + llm_pos_ids_list.append(torch.arange(text_len).view(1, -1).expand(3, -1) + st_idx) + + st_idx = llm_pos_ids_list[-1].max() + 1 if len(llm_pos_ids_list) > 0 else 0 + bos_len = 1 + llm_pos_ids_list.append(torch.arange(bos_len).view(1, -1).expand(3, -1) + st_idx) + + st_idx = llm_pos_ids_list[-1].max() + 1 if len(llm_pos_ids_list) > 0 else 0 + audio_len = ((audio_seqlens[audio_idx] - 1) // 2 + 1 - 2) // 2 + 1 + llm_pos_ids = torch.arange(audio_len).view(1, -1).expand(3, -1) + st_idx + llm_pos_ids_list.append(llm_pos_ids) + + st_idx = llm_pos_ids_list[-1].max() + 1 if len(llm_pos_ids_list) > 0 else 0 + eos_len = 1 + llm_pos_ids_list.append(torch.arange(eos_len).view(1, -1).expand(3, -1) + st_idx) + + st += text_len + bos_len + audio_len + eos_len + audio_idx += 1 + remain_audios -= 1 + + elif min_ed == ed_image: + text_len = min_ed - st - 1 + if text_len != 0: + st_idx = llm_pos_ids_list[-1].max() + 1 if len(llm_pos_ids_list) > 0 else 0 + llm_pos_ids_list.append(torch.arange(text_len).view(1, -1).expand(3, -1) + st_idx) + + st_idx = llm_pos_ids_list[-1].max() + 1 if len(llm_pos_ids_list) > 0 else 0 + bos_len = 1 + llm_pos_ids_list.append(torch.arange(bos_len).view(1, -1).expand(3, -1) + st_idx) + + st_idx = llm_pos_ids_list[-1].max() + 1 if len(llm_pos_ids_list) > 0 else 0 + grid_t = image_grid_thw[image_idx][0] + grid_hs = image_grid_thw[:, 1] + grid_ws = image_grid_thw[:, 2] + t_index = (torch.arange(grid_t) * 1 * position_id_per_seconds).long() + llm_pos_ids = self.get_llm_pos_ids_for_vision( + st_idx, image_idx, spatial_merge_size, t_index, grid_hs, grid_ws + ) + image_len = image_grid_thw[image_idx].prod() // (spatial_merge_size**2) + llm_pos_ids_list.append(llm_pos_ids) + + st_idx = llm_pos_ids_list[-1].max() + 1 if len(llm_pos_ids_list) > 0 else 0 + eos_len = 1 + llm_pos_ids_list.append(torch.arange(eos_len).view(1, -1).expand(3, -1) + st_idx) + + st += text_len + bos_len + image_len + eos_len + image_idx += 1 + remain_images -= 1 + + elif min_ed == ed_video and not use_audio_in_video: + text_len = min_ed - st - 1 + if text_len != 0: + st_idx = llm_pos_ids_list[-1].max() + 1 if len(llm_pos_ids_list) > 0 else 0 + llm_pos_ids_list.append(torch.arange(text_len).view(1, -1).expand(3, -1) + st_idx) + + st_idx = llm_pos_ids_list[-1].max() + 1 if len(llm_pos_ids_list) > 0 else 0 + bos_len = 1 + llm_pos_ids_list.append(torch.arange(bos_len).view(1, -1).expand(3, -1) + st_idx) + + st_idx = llm_pos_ids_list[-1].max() + 1 if len(llm_pos_ids_list) > 0 else 0 + grid_t = video_grid_thw[video_idx][0] + grid_hs = video_grid_thw[:, 1] + grid_ws = video_grid_thw[:, 2] + t_index = ( + torch.arange(grid_t) * second_per_grids[video_idx].cpu().float() * position_id_per_seconds + ).long() + llm_pos_ids = self.get_llm_pos_ids_for_vision( + st_idx, video_idx, spatial_merge_size, t_index, grid_hs, grid_ws + ) + video_len = video_grid_thw[video_idx].prod() // (spatial_merge_size**2) + llm_pos_ids_list.append(llm_pos_ids) + + st_idx = llm_pos_ids_list[-1].max() + 1 if len(llm_pos_ids_list) > 0 else 0 + eos_len = 1 + llm_pos_ids_list.append(torch.arange(eos_len).view(1, -1).expand(3, -1) + st_idx) + + st += text_len + bos_len + video_len + eos_len + video_idx += 1 + remain_videos -= 1 + + elif min_ed == ed_video and use_audio_in_video: + text_len = min_ed - st - 2 + if text_len != 0: + st_idx = llm_pos_ids_list[-1].max() + 1 if len(llm_pos_ids_list) > 0 else 0 + llm_pos_ids_list.append(torch.arange(text_len).view(1, -1).expand(3, -1) + st_idx) + + st_idx = llm_pos_ids_list[-1].max() + 1 if len(llm_pos_ids_list) > 0 else 0 + bos_len = 1 + llm_pos_ids_list.append(torch.arange(bos_len).view(1, -1).expand(3, -1) + st_idx) + llm_pos_ids_list.append(torch.arange(bos_len).view(1, -1).expand(3, -1) + st_idx) + + st_idx = llm_pos_ids_list[-1].max() + 1 if len(llm_pos_ids_list) > 0 else 0 + audio_len = ((audio_seqlens[audio_idx] - 1) // 2 + 1 - 2) // 2 + 1 + audio_llm_pos_ids = torch.arange(audio_len).view(1, -1).expand(3, -1) + st_idx + grid_t = video_grid_thw[video_idx][0] + grid_hs = video_grid_thw[:, 1] + grid_ws = video_grid_thw[:, 2] + + t_index = ( + torch.arange(grid_t) * second_per_grids[video_idx].cpu().float() * position_id_per_seconds + ).long() + video_llm_pos_ids = self.get_llm_pos_ids_for_vision( + st_idx, video_idx, spatial_merge_size, t_index, grid_hs, grid_ws + ) + + t_ntoken_per_chunk = int(position_id_per_seconds * seconds_per_chunk) + video_chunk_indexes = self.get_chunked_index(video_llm_pos_ids[0], t_ntoken_per_chunk, st_idx) + audio_chunk_indexes = self.get_chunked_index(audio_llm_pos_ids[0], t_ntoken_per_chunk, st_idx) + sub_len = 0 + for j in range(max(len(video_chunk_indexes), len(audio_chunk_indexes))): + video_chunk_index = video_chunk_indexes[j] if j < len(video_chunk_indexes) else None + audio_chunk_index = audio_chunk_indexes[j] if j < len(audio_chunk_indexes) else None + if video_chunk_index is not None: + sub_len += video_chunk_index[1] - video_chunk_index[0] + + llm_pos_ids_list.append( + video_llm_pos_ids[:, video_chunk_index[0] : video_chunk_index[1]] + ) + if audio_chunk_index is not None: + sub_len += audio_chunk_index[1] - audio_chunk_index[0] + + llm_pos_ids_list.append( + audio_llm_pos_ids[:, audio_chunk_index[0] : audio_chunk_index[1]] + ) + video_len = video_grid_thw[video_idx].prod() // (spatial_merge_size**2) + + st_idx = llm_pos_ids_list[-1].max() + 1 if len(llm_pos_ids_list) > 0 else 0 + eos_len = 1 + llm_pos_ids_list.append(torch.arange(eos_len).view(1, -1).expand(3, -1) + st_idx) + llm_pos_ids_list.append(torch.arange(eos_len).view(1, -1).expand(3, -1) + st_idx) + + st += text_len + bos_len * 2 + audio_len + video_len + eos_len * 2 + + audio_idx += 1 + video_idx += 1 + remain_videos -= 1 + remain_audios -= 1 + + if st < len(input_tokens): + st_idx = llm_pos_ids_list[-1].max() + 1 if len(llm_pos_ids_list) > 0 else 0 + text_len = len(input_tokens) - st + llm_pos_ids_list.append(torch.arange(text_len).view(1, -1).expand(3, -1) + st_idx) + + llm_positions = torch.cat(llm_pos_ids_list, dim=1).reshape(3, -1) + + if attention_mask is not None: + position_ids[..., i, attention_mask[i]] = llm_positions.to(position_ids.device) + else: + position_ids[..., i, :] = llm_positions.to(position_ids.device) + mrope_position_deltas.append(llm_positions.max() + 1 - len(input_ids)) + mrope_position_deltas = torch.tensor(mrope_position_deltas).unsqueeze(1).to(device=input_ids.device) + + return position_ids, mrope_position_deltas + else: + position_ids = attention_mask.long().cumsum(-1) - 1 + position_ids.masked_fill_(attention_mask == 0, 1) + position_ids = position_ids.unsqueeze(0).expand(3, -1, -1).to(attention_mask.device) + max_position_ids = position_ids.max(0, keepdim=False)[0].max(-1, keepdim=True)[0] + mrope_position_deltas = max_position_ids + 1 - torch.sum(attention_mask, dim=-1, keepdim=True) + + return position_ids, mrope_position_deltas + + +############################ +# Start Thinker # +############################ + + +@dataclass +@auto_docstring( + custom_intro=""" + Base class for Qwen2.5OmniThinker causal language model (or autoregressive) outputs. + """ +) +class Qwen2_5OmniThinkerCausalLMOutputWithPast(ModelOutput): + r""" + loss (`torch.FloatTensor` of shape `(1,)`, *optional*, returned when `labels` is provided): + Language modeling loss (for next-token prediction). + logits (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.vocab_size)`, *optional*): + Prediction scores of the language modeling head (scores for each vocabulary token before SoftMax). + past_key_values (`Cache`, *optional*, returned when `use_cache=True` is passed or when `config.use_cache=True`): + It is a [`~cache_utils.Cache`] instance. For more details, see our [kv cache guide](https://huggingface.co/docs/transformers/en/kv_cache). + + Contains pre-computed hidden-states (key and values in the self-attention blocks) that can be used (see + `past_key_values` input) to speed up sequential decoding. + rope_deltas (`torch.LongTensor` of shape `(batch_size, )`, *optional*): + The rope index difference between sequence length and multimodal rope. + """ + + loss: torch.FloatTensor | None = None + logits: torch.FloatTensor | None = None + past_key_values: Cache | None = None + hidden_states: tuple[torch.FloatTensor] | None = None + attentions: tuple[torch.FloatTensor] | None = None + rope_deltas: torch.LongTensor | None = None + + +class Qwen2_5OmniAudioAttention(nn.Module): + """Multi-headed attention from 'Attention Is All You Need' paper""" + + def __init__( + self, + config: Qwen2_5OmniAudioEncoderConfig, + ): + super().__init__() + self.embed_dim = config.d_model + self.num_heads = config.encoder_attention_heads + self.dropout = config.attention_dropout + self.head_dim = self.embed_dim // self.num_heads + self.num_key_value_groups = 1 # needed for eager attention + self.config = config + + if (self.head_dim * self.num_heads) != self.embed_dim: + raise ValueError( + f"embed_dim must be divisible by num_heads (got `embed_dim`: {self.embed_dim}" + f" and `num_heads`: {self.num_heads})." + ) + self.scaling = self.head_dim**-0.5 + self.attention_dropout = 0.0 + self.is_decoder = False + self.is_causal = False + + self.k_proj = nn.Linear(self.embed_dim, self.embed_dim, bias=False) + self.v_proj = nn.Linear(self.embed_dim, self.embed_dim, bias=True) + self.q_proj = nn.Linear(self.embed_dim, self.embed_dim, bias=True) + self.out_proj = nn.Linear(self.embed_dim, self.embed_dim, bias=True) + + def forward( + self, + hidden_states: torch.Tensor, + cu_seqlens: torch.Tensor | None = None, + attention_mask: torch.Tensor | None = None, + **kwargs, + ) -> tuple[torch.Tensor, torch.Tensor | None, tuple[torch.Tensor] | None]: + """Input shape: Batch x Time x Channel""" + + seq_length, _ = hidden_states.size() + + query_states = self.q_proj(hidden_states).reshape(seq_length, self.num_heads, -1) + key_states = self.k_proj(hidden_states).reshape(seq_length, self.num_heads, -1) + value_states = self.v_proj(hidden_states).reshape(seq_length, self.num_heads, -1) + + query_states = query_states.transpose(0, 1).unsqueeze(0) + key_states = key_states.transpose(0, 1).unsqueeze(0) + value_states = value_states.transpose(0, 1).unsqueeze(0) + max_seqlen = (cu_seqlens[1:] - cu_seqlens[:-1]).max() + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, eager_attention_forward + ) + + attn_output, _ = attention_interface( + self, + query_states, + key_states, + value_states, + attention_mask=attention_mask, + dropout=0.0 if not self.training else self.attention_dropout, + scaling=self.scaling, + cu_seq_lens_q=cu_seqlens, # pass cu seq lens for FA2 + cu_seq_lens_k=cu_seqlens, + max_length_q=max_seqlen, + max_length_k=max_seqlen, + is_causal=False, + **kwargs, + ) + + attn_output = attn_output.reshape(seq_length, -1).contiguous() + attn_output = self.out_proj(attn_output) + + return attn_output + + +class Qwen2_5OmniAudioEncoderLayer(Qwen2AudioEncoderLayer): + def __init__(self, config: Qwen2_5OmniAudioEncoderConfig): + super().__init__(config) + self.self_attn = Qwen2_5OmniAudioAttention(config) + + def forward( + self, + hidden_states: torch.Tensor, + cu_seqlens: torch.Tensor, + attention_mask: torch.Tensor | None = None, + **kwargs, + ) -> torch.Tensor: + residual = hidden_states + hidden_states = self.self_attn_layer_norm(hidden_states) + hidden_states = self.self_attn( + hidden_states=hidden_states, + cu_seqlens=cu_seqlens, + attention_mask=attention_mask, + **kwargs, + ) + hidden_states = residual + hidden_states + residual = hidden_states + hidden_states = self.final_layer_norm(hidden_states) + hidden_states = self.fc1(hidden_states) + hidden_states = self.activation_fn(hidden_states) + hidden_states = self.fc2(hidden_states) + hidden_states = residual + hidden_states + + if hidden_states.dtype == torch.float16: + clamp_value = torch.finfo(hidden_states.dtype).max - 1000 + hidden_states = torch.clamp(hidden_states, min=-clamp_value, max=clamp_value) + + outputs = (hidden_states,) + + return outputs + + +class SinusoidsPositionEmbedding(nn.Module): + def __init__(self, length, channels, max_timescale=10000): + super().__init__() + self.length = length + self.channels = channels + self.max_timescale = max_timescale + if channels % 2 != 0: + raise ValueError("SinusoidsPositionEmbedding needs even channels input") + log_timescale_increment = np.log(max_timescale) / (channels // 2 - 1) + inv_timescales = torch.exp(-log_timescale_increment * torch.arange(channels // 2).float()) + scaled_time = torch.arange(length)[:, np.newaxis] * inv_timescales[np.newaxis, :] + self.register_buffer( + "positional_embedding", + torch.cat([torch.sin(scaled_time), torch.cos(scaled_time)], dim=1), + persistent=False, + ) + + def forward(self, seqlen: int): + return self.positional_embedding[:seqlen, :] + + +@auto_docstring( + custom_intro=""" + Transformer encoder consisting of *config.encoder_layers* self attention layers. Each layer is a + [`Qwen2_5OmniAudioEncoderLayer`]. + """ +) +class Qwen2_5OmniAudioEncoder(Qwen2_5OmniPreTrainedModel): + config: Qwen2_5OmniAudioEncoderConfig + main_input_name = "input_features" + input_modalities = "audio" + _no_split_modules = ["Qwen2_5OmniAudioEncoderLayer"] + _supports_sdpa = True + _can_record_outputs = { + "hidden_states": Qwen2_5OmniAudioEncoderLayer, + "attentions": Qwen2_5OmniAudioAttention, + } + + def __init__(self, config: Qwen2_5OmniAudioEncoderConfig): + super().__init__(config) + self.dropout = config.dropout + + embed_dim = config.d_model + self.num_mel_bins = config.num_mel_bins + self.max_source_positions = config.max_source_positions + self.embed_scale = math.sqrt(embed_dim) if config.scale_embedding else 1.0 + self.n_window = config.n_window + self.conv1 = nn.Conv1d(self.num_mel_bins, embed_dim, kernel_size=3, padding=1) + self.conv2 = nn.Conv1d(embed_dim, embed_dim, kernel_size=3, stride=2, padding=1) + self.positional_embedding = SinusoidsPositionEmbedding(self.max_source_positions, embed_dim) + self.audio_bos_eos_token = nn.Embedding(2, config.output_dim) + self.layers = nn.ModuleList([Qwen2_5OmniAudioEncoderLayer(config) for _ in range(config.encoder_layers)]) + self.ln_post = nn.LayerNorm(config.d_model) + self.avg_pooler = nn.AvgPool1d(2, stride=2) + self.proj = nn.Linear(config.d_model, config.output_dim) + self.gradient_checkpointing = False + # Initialize weights and apply final processing + self.post_init() + + def _freeze_parameters(self): + for param in self.parameters(): + param.requires_grad = False + self._requires_grad = False + + def get_input_embeddings(self) -> nn.Module: + return self.conv1 + + def set_input_embeddings(self, value: nn.Module): + self.conv1 = value + + def _prepare_attention_mask(self, inputs_tensor: torch.Tensor, cu_seqlens: torch.Tensor) -> torch.Tensor: + # Flash Attention 2 doesn't need a 4D mask and relies on `cu_seqlens/max_seqlen` + # NOTE: the created attention masl only approximates the ragged FA2 attention by + # allowing bidirectional attention within `cu_seqlens` blocks, and not attending between + # blocks. Though it will not be a 100% match for FA2's `varlen` path + if is_flash_attention_requested(self.config): + return None + + seq_length = inputs_tensor.shape[0] + attention_mask = torch.full( + [1, 1, seq_length, seq_length], + torch.finfo(inputs_tensor.dtype).min, + device=inputs_tensor.device, + dtype=inputs_tensor.dtype, + ) + for i in range(1, len(cu_seqlens)): + attention_mask[..., cu_seqlens[i - 1] : cu_seqlens[i], cu_seqlens[i - 1] : cu_seqlens[i]] = 0 + return attention_mask + + @merge_with_config_defaults + @capture_outputs(tie_last_hidden_states=False) + @auto_docstring + def forward(self, input_features, feature_lens=None, aftercnn_lens=None, **kwargs: Unpack[TransformersKwargs]): + r""" + feature_lens (`torch.LongTensor` of shape `(batch_size,)`): + mel length + aftercnn_lens (`torch.LongTensor` of shape `(batch_size,)`): + mel length after cnn + """ + chunk_num = torch.ceil(feature_lens / (self.n_window * 2)).long() + + chunk_lengths = torch.full((chunk_num.sum(),), self.n_window * 2, dtype=torch.long, device=feature_lens.device) + tail_chunk_index = F.pad(chunk_num, (1, 0), value=-1).cumsum(0)[1:] + chunk_lengths[tail_chunk_index] = feature_lens % (self.n_window * 2) + chunk_lengths = torch.where(chunk_lengths == 0, self.n_window * 2, chunk_lengths) + + chunk_list = input_features.split(chunk_lengths.tolist(), dim=1) + padded_feature, padded_mask, padded_mask_after_cnn = self.padded_and_mask_function( + chunk_list, chunk_lengths, padding_value=0, padding_side="right" + ) + padded_embed = nn.functional.gelu(self.conv1(padded_feature)) * padded_mask + padded_embed = nn.functional.gelu(self.conv2(padded_embed)).transpose(1, 2) + + padded_embed = padded_embed + self.positional_embedding.positional_embedding[ + : padded_embed.shape[1], : + ].unsqueeze(0).to(padded_embed.dtype) + hidden_states = padded_embed[padded_mask_after_cnn] + cu_seqlens = torch.cat( + ( + torch.zeros(1, device=padded_mask_after_cnn.device, dtype=torch.int32), + padded_mask_after_cnn.sum(1).cumsum(0), + ) + ).to(torch.int32) + attention_mask = self._prepare_attention_mask(hidden_states, cu_seqlens) + + for encoder_layer in self.layers: + layer_outputs = encoder_layer( + hidden_states, + cu_seqlens=cu_seqlens, + attention_mask=attention_mask, + **kwargs, + ) + hidden_states = layer_outputs[0] + + hidden_states_list = hidden_states.split(aftercnn_lens.tolist(), dim=0) + token_audio_list = [] + for each_audio_states in hidden_states_list: + each_audio_states = self.avg_pooler(each_audio_states.transpose(0, 1)).transpose_(0, 1) + each_audio_states = self.ln_post(each_audio_states) + each_audio_states = self.proj(each_audio_states) + token_audio_list.append(each_audio_states) + token_audio = torch.cat(token_audio_list, dim=0) + return BaseModelOutputWithPooling(last_hidden_state=token_audio) + + def padded_and_mask_function(self, tensor_list, tensor_len, padding_value=0, padding_side="right"): + """ + Pads a sequence of tensors to their maximum length on indicated `padding_side`. + Then prepares a mask so that pad tokens are not attended to. + """ + max_len = tensor_len.max() + dim = tensor_list[0].shape[0] + padded_tensor = torch.full( + size=(len(tensor_list), dim, max_len), + fill_value=padding_value, + dtype=self.dtype, + device=tensor_list[0].device, + ) + + batch_mask = torch.zeros( + (len(tensor_len), max_len), + dtype=torch.long, + device=padded_tensor.device, + ) + for i, length in enumerate(tensor_len): + batch_mask[i, :length] = 1 + padded_tensor[i, :, :length] = tensor_list[i] + + feature_lens_after_cnn = (tensor_len - 1) // 2 + 1 + max_len_after_cnn = feature_lens_after_cnn.max() + batch_mask_after_cnn = torch.zeros( + (len(tensor_len), max_len_after_cnn), + dtype=torch.long, + device=padded_tensor.device, + ) + for i, length in enumerate(feature_lens_after_cnn): + batch_mask_after_cnn[i, :length] = 1 + return ( + padded_tensor, + batch_mask.unsqueeze(1), + batch_mask_after_cnn.bool(), + ) + + # Ignore copy + def _get_feat_extract_output_lengths(self, input_lengths: torch.LongTensor): + """ + Computes the output length of the convolutional layers and the output length of the audio encoder + """ + input_lengths = (input_lengths - 1) // 2 + 1 + output_lengths = (input_lengths - 2) // 2 + 1 + return input_lengths, output_lengths + + +def apply_rotary_pos_emb_vision(tensor: torch.Tensor, freqs: torch.Tensor) -> torch.Tensor: + orig_dtype = tensor.dtype + tensor = tensor.float() + cos = freqs.cos() + sin = freqs.sin() + cos = cos.unsqueeze(1).repeat(1, 1, 2).unsqueeze(0).float() + sin = sin.unsqueeze(1).repeat(1, 1, 2).unsqueeze(0).float() + output = (tensor * cos) + (rotate_half(tensor) * sin) + output = output.to(orig_dtype) + return output + + +class Qwen2_5OmniVisionAttention(nn.Module): + def __init__(self, config: Qwen2_5OmniVisionEncoderConfig = None) -> None: + super().__init__() + self.dim = config.hidden_size + self.num_heads = config.num_heads + self.head_dim = self.dim // self.num_heads + self.q = nn.Linear(self.dim, self.dim, bias=True) + self.k = nn.Linear(self.dim, self.dim, bias=True) + self.v = nn.Linear(self.dim, self.dim, bias=True) + self.proj = nn.Linear(self.dim, self.dim) + self.scaling = self.head_dim**-0.5 + self.num_key_value_groups = 1 # needed for eager attention + self.config = config + self.attention_dropout = 0.0 + self.is_causal = False + + def forward( + self, + hidden_states: torch.Tensor, + cu_seqlens: torch.Tensor, + rotary_pos_emb: torch.Tensor | None = None, + **kwargs, + ) -> torch.Tensor: + seq_length = hidden_states.shape[0] + query_states = self.q(hidden_states).reshape(seq_length, self.num_heads, -1) + key_states = self.k(hidden_states).reshape(seq_length, self.num_heads, -1) + value_states = self.v(hidden_states).reshape(seq_length, self.num_heads, -1) + query_states = apply_rotary_pos_emb_vision(query_states.unsqueeze(0), rotary_pos_emb).squeeze(0) + key_states = apply_rotary_pos_emb_vision(key_states.unsqueeze(0), rotary_pos_emb).squeeze(0) + + query_states = query_states.transpose(0, 1).unsqueeze(0) + key_states = key_states.transpose(0, 1).unsqueeze(0) + value_states = value_states.transpose(0, 1).unsqueeze(0) + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, eager_attention_forward + ) + + if is_flash_attention_requested(self.config): + # Flash Attention 2: Use cu_seqlens for variable length attention + max_seqlen = (cu_seqlens[1:] - cu_seqlens[:-1]).max() + attn_output, _ = attention_interface( + self, + query_states, + key_states, + value_states, + attention_mask=None, + scaling=self.scaling, + dropout=0.0 if not self.training else self.attention_dropout, + cu_seq_lens_q=cu_seqlens, + cu_seq_lens_k=cu_seqlens, + max_length_q=max_seqlen, + max_length_k=max_seqlen, + is_causal=False, + **kwargs, + ) + else: + # Other implementations: Process each chunk separately + lengths = cu_seqlens[1:] - cu_seqlens[:-1] + splits = [ + torch.split(tensor, lengths.tolist(), dim=2) for tensor in (query_states, key_states, value_states) + ] + + attn_outputs = [ + attention_interface( + self, + q, + k, + v, + attention_mask=None, + scaling=self.scaling, + dropout=0.0 if not self.training else self.attention_dropout, + is_causal=False, + **kwargs, + )[0] + for q, k, v in zip(*splits) + ] + attn_output = torch.cat(attn_outputs, dim=1) + + attn_output = attn_output.reshape(seq_length, -1).contiguous() + attn_output = self.proj(attn_output) + return attn_output + + +class Qwen2_5OmniVisionBlock(Qwen2_5_VLVisionBlock): + def __init__(self, config: Qwen2_5OmniVisionEncoderConfig) -> None: + super().__init__(config, config._attn_implementation) + self.attn = Qwen2_5OmniVisionAttention(config=config) + + def forward( + self, + hidden_states: torch.Tensor, + cu_seqlens: torch.Tensor, + rotary_pos_emb: torch.Tensor | None = None, + **kwargs, + ) -> torch.Tensor: + hidden_states = hidden_states + self.attn( + self.norm1(hidden_states), + cu_seqlens=cu_seqlens, + rotary_pos_emb=rotary_pos_emb, + **kwargs, + ) + hidden_states = hidden_states + self.mlp(self.norm2(hidden_states)) + return hidden_states + + +class Qwen2_5_VisionRotaryEmbedding(Qwen2_5_VisionRotaryEmbedding): + pass + + +class Qwen2_5OmniVisionEncoder(Qwen2_5_VisionTransformerPretrainedModel): + config: Qwen2_5OmniVisionEncoderConfig + input_modalities = ("image", "video") + _no_split_modules = ["Qwen2_5OmniVisionBlock"] + _input_embed_layer = "patch_embed" + _can_record_outputs = { + "hidden_states": Qwen2_5OmniVisionBlock, + "attentions": Qwen2_5OmniVisionAttention, + } + + def __init__(self, config: Qwen2_5OmniVisionEncoderConfig, *inputs, **kwargs) -> None: + super().__init__(config, *inputs, **kwargs) + self.blocks = nn.ModuleList([Qwen2_5OmniVisionBlock(config) for _ in range(config.depth)]) + + @merge_with_config_defaults + @capture_outputs + def forward( + self, hidden_states: torch.Tensor, grid_thw: torch.Tensor, **kwargs: Unpack[TransformersKwargs] + ) -> tuple | BaseModelOutputWithPooling: + """ + Args: + hidden_states (`torch.Tensor` of shape `(seq_len, hidden_size)`): + The final hidden states of the model. + grid_thw (`torch.Tensor` of shape `(num_images_or_videos, 3)`): + The temporal, height and width of feature shape of each image in LLM. + + Returns: + `torch.Tensor`: hidden_states. + """ + hidden_states = self.patch_embed(hidden_states) + rotary_pos_emb = self.rot_pos_emb(grid_thw) + + window_index, cu_window_seqlens = self.get_window_index(grid_thw) + cu_window_seqlens = torch.tensor( + cu_window_seqlens, + device=hidden_states.device, + dtype=grid_thw.dtype if torch.jit.is_tracing() else torch.int32, + ) + cu_window_seqlens = torch.unique_consecutive(cu_window_seqlens) + + seq_len, _ = hidden_states.size() + hidden_states = hidden_states.reshape(seq_len // self.spatial_merge_unit, self.spatial_merge_unit, -1) + hidden_states = hidden_states[window_index, :, :] + hidden_states = hidden_states.reshape(seq_len, -1) + rotary_pos_emb = rotary_pos_emb.reshape(seq_len // self.spatial_merge_unit, self.spatial_merge_unit, -1) + rotary_pos_emb = rotary_pos_emb[window_index, :, :] + rotary_pos_emb = rotary_pos_emb.reshape(seq_len, -1) + + cu_seqlens = torch.repeat_interleave(grid_thw[:, 1] * grid_thw[:, 2], grid_thw[:, 0]).cumsum( + dim=0, + # Select dtype based on the following factors: + # - FA2 requires that cu_seqlens_q must have dtype int32 + # - torch.onnx.export requires that cu_seqlens_q must have same dtype as grid_thw + # See https://github.com/huggingface/transformers/pull/34852 for more information + dtype=grid_thw.dtype if torch.jit.is_tracing() else torch.int32, + ) + cu_seqlens = F.pad(cu_seqlens, (1, 0), value=0) + + # Modification here + for layer_num, blk in enumerate(self.blocks): + if layer_num in self.fullatt_block_indexes: + cu_seqlens_now = cu_seqlens + else: + cu_seqlens_now = cu_window_seqlens + + hidden_states = blk( + hidden_states, + cu_seqlens=cu_seqlens_now, + rotary_pos_emb=rotary_pos_emb, + **kwargs, + ) + + merged_hidden_states = self.merger(hidden_states) + reverse_indices = torch.argsort(window_index) + merged_hidden_states = merged_hidden_states[reverse_indices, :] + + return BaseModelOutputWithPooling( + last_hidden_state=hidden_states, + pooler_output=merged_hidden_states, + ) + + +class Qwen2_5OmniRotaryEmbedding(Qwen2VLRotaryEmbedding): + def __init__(self, config: Qwen2_5OmniThinkerConfig, device=None): + super().__init__(config, device) + + +# It's same as `Qwen2_5_VLAttention`, but talker model's hidden_size isn't divisible by num_heads. +# Removes the value error as a workaround. +class Qwen2_5OmniAttention(Qwen2_5_VLAttention): + def __init__(self, config: Qwen2_5OmniConfig, layer_idx: int | None = None): + nn.Module.__init__(self) + self.config = config + self.layer_idx = layer_idx + if layer_idx is None: + logger.warning_once( + f"Instantiating {self.__class__.__name__} without passing `layer_idx` is not recommended and will " + "to errors during the forward call, if caching is used. Please make sure to provide a `layer_idx` " + "when creating this class." + ) + + self.hidden_size = config.hidden_size + self.num_heads = config.num_attention_heads + self.head_dim = getattr(config, "head_dim", self.hidden_size // self.num_heads) + self.num_key_value_heads = config.num_key_value_heads + self.num_key_value_groups = self.num_heads // self.num_key_value_heads + self.is_causal = True + self.attention_dropout = config.attention_dropout + self.rope_parameters = config.rope_parameters + self.scaling = self.head_dim**-0.5 + + self.q_proj = nn.Linear(self.hidden_size, self.num_heads * self.head_dim, bias=True) + self.k_proj = nn.Linear(self.hidden_size, self.num_key_value_heads * self.head_dim, bias=True) + self.v_proj = nn.Linear(self.hidden_size, self.num_key_value_heads * self.head_dim, bias=True) + self.o_proj = nn.Linear(self.num_heads * self.head_dim, self.hidden_size, bias=False) + self.layer_type = config.layer_types[layer_idx] if hasattr(config, "layer_types") else None + self.sliding_window = config.sliding_window if self.layer_type == "sliding_attention" else None + + +class Qwen2MLP(Qwen2_5_VLMLP): + pass + + +class Qwen2_5OmniThinkerTextModel(Qwen2_5_VLTextModel): + config: Qwen2_5OmniTextConfig + _no_split_modules = ["Qwen2_5OmniDecoderLayer"] + + def __init__(self, config: Qwen2_5OmniTextConfig): + super().__init__(config) + + +@auto_docstring( + custom_intro=""" + The Qwen2.5OmniThinker model which consists of a audio backbone and a language model. + """ +) +class Qwen2_5OmniThinkerForConditionalGeneration(Qwen2_5OmniPreTrainedModelForConditionalGeneration, GenerationMixin): + config: Qwen2_5OmniThinkerConfig + base_model_prefix = "thinker" + _tied_weights_keys = {"lm_head.weight": "model.embed_tokens.weight"} + _no_split_modules = ["Qwen2_5OmniAudioEncoder", "Qwen2_5OmniVisionEncoder"] + + def __init__(self, config: Qwen2_5OmniThinkerConfig): + super().__init__(config) + self.audio_tower = Qwen2_5OmniAudioEncoder._from_config(config.audio_config) + self.visual = Qwen2_5OmniVisionEncoder._from_config(config.vision_config) + self.vocab_size = config.text_config.vocab_size + self.model = Qwen2_5OmniThinkerTextModel._from_config(config.text_config) + self.lm_head = nn.Linear(config.text_config.hidden_size, config.text_config.vocab_size, bias=False) + self.spatial_merge_size = config.vision_config.spatial_merge_size + self.rope_deltas = None + self.post_init() + + def get_input_embeddings(self): + return self.model.get_input_embeddings() + + def set_input_embeddings(self, value): + self.model.set_input_embeddings(value) + + @can_return_tuple + @auto_docstring + def get_video_features( + self, + pixel_values_videos: torch.FloatTensor, + video_grid_thw: torch.LongTensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple | BaseModelOutputWithPooling: + r""" + pixel_values_videos (`torch.FloatTensor` of shape `(batch_size, num_channels, image_size, image_size)`): + The tensors corresponding to the input videos. + video_grid_thw (`torch.LongTensor` of shape `(num_videos, 3)`, *optional*): + The temporal, height and width of feature shape of each video in LLM. + """ + pixel_values_videos = pixel_values_videos.type(self.visual.dtype) + return self.visual(pixel_values_videos, grid_thw=video_grid_thw, **kwargs) + + @can_return_tuple + @auto_docstring + def get_image_features( + self, + pixel_values: torch.FloatTensor, + image_grid_thw: torch.LongTensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple | BaseModelOutputWithPooling: + r""" + pixel_values (`torch.FloatTensor` of shape `(batch_size, num_channels, image_size, image_size)`): + The tensors corresponding to the input images. + image_grid_thw (`torch.LongTensor` of shape `(num_images, 3)`, *optional*): + The temporal, height and width of feature shape of each image in LLM. + """ + pixel_values = pixel_values.type(self.visual.dtype) + return self.visual(pixel_values, grid_thw=image_grid_thw, **kwargs) + + @can_return_tuple + @auto_docstring + def get_audio_features( + self, + input_features: torch.FloatTensor, + feature_attention_mask: torch.LongTensor | None = None, + audio_feature_lengths: torch.LongTensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple | BaseModelOutputWithPooling: + r""" + input_features (`torch.FloatTensor`): + The tensors corresponding to the input audios. + feature_attention_mask (`torch.LongTensor`, *optional*): + Mask to avoid performing attention on padding feature indices. Mask values selected in `[0, 1]`: + audio_feature_lengths (`torch.LongTensor` of shape `(num_audios)`, *optional*): + The length of feature shape of each audio in LLM. + """ + if feature_attention_mask is not None: + audio_feature_lengths = torch.sum(feature_attention_mask, dim=1) + input_features = input_features.permute(0, 2, 1)[feature_attention_mask.bool()].permute(1, 0) + else: + audio_feature_lengths = None + + audio_feat_lengths, audio_output_lengths = self.audio_tower._get_feat_extract_output_lengths( + audio_feature_lengths if audio_feature_lengths is not None else feature_attention_mask.sum(-1) + ) + feature_lens = audio_feature_lengths if audio_feature_lengths is not None else feature_attention_mask.sum(-1) + audio_outputs = self.audio_tower( + input_features, + feature_lens=feature_lens, + aftercnn_lens=audio_feat_lengths, + return_dict=True, + **kwargs, + ) + if audio_outputs.last_hidden_state.shape[0] != sum(audio_output_lengths.tolist()): + raise ValueError("length of audio_features should match audio_output_lengths") + + return audio_outputs + + def get_placeholder_mask( + self, + input_ids: torch.LongTensor, + inputs_embeds: torch.FloatTensor, + image_features: torch.FloatTensor | None = None, + video_features: torch.FloatTensor | None = None, + ): + """ + Obtains multimodal placeholder mask from `input_ids` or `inputs_embeds`, and checks that the placeholder token count is + equal to the length of multimodal features. If the lengths are different, an error is raised. + """ + if input_ids is None: + special_image_mask = inputs_embeds == self.get_input_embeddings()( + torch.tensor(self.config.image_token_id, dtype=torch.long, device=inputs_embeds.device) + ) + special_image_mask = special_image_mask.all(-1) + special_video_mask = inputs_embeds == self.get_input_embeddings()( + torch.tensor(self.config.video_token_id, dtype=torch.long, device=inputs_embeds.device) + ) + special_video_mask = special_video_mask.all(-1) + special_audio_mask = ( + inputs_embeds + == self.get_input_embeddings()( + torch.tensor(self.config.audio_token_id, dtype=torch.long, device=inputs_embeds.device) + ) + ).all(-1) + else: + special_image_mask = input_ids == self.config.image_token_id + special_video_mask = input_ids == self.config.video_token_id + special_audio_mask = input_ids == self.config.audio_token_id + + n_image_tokens = special_image_mask.sum() + special_image_mask = special_image_mask.unsqueeze(-1).expand_as(inputs_embeds).to(inputs_embeds.device) + if image_features is not None: + torch_compilable_check( + inputs_embeds[special_image_mask].numel() == image_features.numel(), + f"Image features and image tokens do not match, tokens: {n_image_tokens}, features: {image_features.shape[0]}", + ) + + n_video_tokens = special_video_mask.sum() + special_video_mask = special_video_mask.unsqueeze(-1).expand_as(inputs_embeds).to(inputs_embeds.device) + if video_features is not None: + torch_compilable_check( + inputs_embeds[special_video_mask].numel() == video_features.numel(), + f"Video features and video tokens do not match, tokens: {n_video_tokens}, features: {video_features.shape[0]}", + ) + + special_audio_mask = special_audio_mask.unsqueeze(-1).expand_as(inputs_embeds).to(inputs_embeds.device) + return special_image_mask, special_video_mask, special_audio_mask + + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + input_features: torch.FloatTensor | None = None, + pixel_values: torch.FloatTensor | None = None, + pixel_values_videos: torch.FloatTensor | None = None, + image_grid_thw: torch.LongTensor | None = None, + video_grid_thw: torch.LongTensor | None = None, + attention_mask: torch.Tensor | None = None, + feature_attention_mask: torch.Tensor | None = None, + audio_feature_lengths: torch.LongTensor | None = None, + position_ids: torch.LongTensor | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.FloatTensor | None = None, + rope_deltas: torch.LongTensor | None = None, + labels: torch.LongTensor | None = None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + use_audio_in_video: bool | None = None, + cache_position: torch.LongTensor | None = None, + video_second_per_grid: torch.LongTensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple | Qwen2_5OmniThinkerCausalLMOutputWithPast: + r""" + image_grid_thw (`torch.LongTensor` of shape `(num_images, 3)`, *optional*): + The temporal, height and width of feature shape of each image in LLM. + video_grid_thw (`torch.LongTensor` of shape `(num_videos, 3)`, *optional*): + The temporal, height and width of feature shape of each video in LLM. + feature_attention_mask (`torch.Tensor` of shape `(batch_size, feature_sequence_length)`, *optional*): + Mask to avoid performing attention on padding feature indices. Mask values selected in `[0, 1]`: + + - 1 for tokens that are **not masked**, + - 0 for tokens that are **masked**. + audio_feature_lengths (`torch.LongTensor` of shape `(num_audios)`, *optional*): + The length of feature shape of each audio in LLM. + rope_deltas (`torch.LongTensor` of shape `(batch_size, )`, *optional*): + The rope index difference between sequence length and multimodal rope. + labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Labels for computing the masked language modeling loss. Indices should either be in `[0, ..., + config.vocab_size]` or -100 (see `input_ids` docstring). Tokens with indices set to `-100` are ignored + (masked), the loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]`. + use_audio_in_video (`bool`, *optional*): + Whether or not use audio track in video, should same as the parameter in `process_audio_info`. + video_second_per_grid (`torch.LongTensor` of shape `(num_videos)`, *optional*): + Number of seconds per grid for each video, used for temporal feature mapping. + + Example: + + ```python + >>> from io import BytesIO + >>> from urllib.request import urlopen + >>> import librosa + >>> from qwen_vl_utils import process_vision_info + >>> from transformers import Qwen2_5OmniProcessor, Qwen2_5OmniThinkerForConditionalGeneration + + >>> thinker = Qwen2_5OmniThinkerForConditionalGeneration.from_pretrained("Qwen/Qwen2.5-Omni-7B") + >>> processor = Qwen2_5OmniProcessor.from_pretrained("Qwen/Qwen2.5-Omni-7B") + + >>> conversations = [ + >>> {'role': 'system', 'content': 'You are a helpful voice chat bot, and please respond to me in a casual conversation manner using random voice.'}, + >>> {"role": "user", "content": [ + >>> {"type": "image", "image_url": "https://www.ilankelman.org/stopsigns/australia.jpg"}, + >>> {"type": "audio", "audio_url": "https://qianwen-res.oss-cn-beijing.aliyuncs.com/Qwen2-Audio/audio/glass-breaking-151256.mp3"}, + >>> ]}, + >>> ] + + >>> text = processor.apply_chat_template(conversation, add_generation_prompt=True, tokenize=False) + >>> audios = [ librosa.load(BytesIO(urlopen( conversations[1]['content'][1]['audio_url'] ).read()), sr=self.processor.feature_extractor.sampling_rate) ] + >>> images, videos = process_vision_info(conversations) + >>> inputs = processor(text=text, audio=audios, images=images, videos=videos, return_tensors="pt", padding=True) + + >>> # Generate + >>> inputs['use_audio_in_video'] = `True` or `False` + >>> generation = thinker.generate(**inputs, max_new_tokens=2048) + >>> generate_ids = generation[:, inputs.input_ids.size(1):] + + >>> response = processor.batch_decode(generate_ids, skip_special_tokens=True, clean_up_tokenization_spaces=False)[0] + ```""" + + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + if inputs_embeds is None: + # 1. Extract the input embeddings + inputs_embeds = self.get_input_embeddings()(input_ids) + + # 2. Merge text , audios , image and video + if input_features is not None: + audio_features = self.get_audio_features( + input_features, + feature_attention_mask=feature_attention_mask, + audio_feature_lengths=audio_feature_lengths, + return_dict=True, + ).last_hidden_state + audio_features = audio_features.to(inputs_embeds.device, inputs_embeds.dtype) + _, _, audio_mask = self.get_placeholder_mask(input_ids, inputs_embeds=inputs_embeds) + inputs_embeds = inputs_embeds.masked_scatter(audio_mask, audio_features) + + if pixel_values is not None: + image_embeds = self.get_image_features(pixel_values, image_grid_thw, return_dict=True).pooler_output + image_embeds = image_embeds.to(inputs_embeds.device, inputs_embeds.dtype) + image_mask, _, _ = self.get_placeholder_mask( + input_ids, inputs_embeds=inputs_embeds, image_features=image_embeds + ) + inputs_embeds = inputs_embeds.masked_scatter(image_mask, image_embeds) + + if pixel_values_videos is not None: + video_embeds = self.get_video_features(pixel_values_videos, video_grid_thw, return_dict=True).pooler_output + video_embeds = video_embeds.to(inputs_embeds.device, inputs_embeds.dtype) + _, video_mask, _ = self.get_placeholder_mask( + input_ids, inputs_embeds=inputs_embeds, video_features=video_embeds + ) + inputs_embeds = inputs_embeds.masked_scatter(video_mask, video_embeds) + + if feature_attention_mask is not None: + audio_feature_lengths = torch.sum(feature_attention_mask, dim=1) + else: + audio_feature_lengths = None + + if attention_mask is not None and position_ids is None: + past_key_values_length = 0 if past_key_values is None else past_key_values.get_seq_length() + if past_key_values_length == 0 or self.rope_deltas is None: + delta0 = (1 - attention_mask).sum(dim=-1).unsqueeze(1) + position_ids, rope_deltas = self.get_rope_index( + input_ids, + image_grid_thw, + video_grid_thw, + attention_mask, + use_audio_in_video, + audio_feature_lengths, + video_second_per_grid, + ) + rope_deltas = rope_deltas - delta0 + self.rope_deltas = rope_deltas + else: + batch_size, seq_length = input_ids.shape + delta = (past_key_values_length + self.rope_deltas).to(input_ids.device) + position_ids = torch.arange(seq_length, device=input_ids.device) + position_ids = position_ids.view(1, -1).expand(batch_size, -1) + position_ids = position_ids.add(delta) + position_ids = position_ids.unsqueeze(0).expand(3, -1, -1) + + outputs = self.model( + attention_mask=attention_mask, + position_ids=position_ids, + past_key_values=past_key_values, + inputs_embeds=inputs_embeds, + use_cache=use_cache, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + cache_position=cache_position, + **kwargs, + ) + + hidden_states = outputs[0] + logits = self.lm_head(hidden_states) + + loss = None + if labels is not None: + loss = self.loss_function( + logits=logits, labels=labels, vocab_size=self.config.get_text_config().vocab_size + ) + + if not return_dict: + output = (logits,) + outputs + return (loss,) + output if loss is not None else output + + return Qwen2_5OmniThinkerCausalLMOutputWithPast( + loss=loss, + logits=logits, + past_key_values=outputs.past_key_values, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + rope_deltas=self.rope_deltas, + ) + + def prepare_inputs_for_generation( + self, + input_ids, + past_key_values=None, + attention_mask=None, + inputs_embeds=None, + cache_position=None, + position_ids=None, + use_cache=True, + pixel_values=None, + pixel_values_videos=None, + image_grid_thw=None, + video_grid_thw=None, + input_features=None, + feature_attention_mask=None, + use_audio_in_video=False, + video_second_per_grid=None, + is_first_iteration=False, + **kwargs, + ): + model_inputs = super().prepare_inputs_for_generation( + input_ids, + past_key_values=past_key_values, + attention_mask=attention_mask, + inputs_embeds=inputs_embeds, + cache_position=cache_position, + position_ids=position_ids, + use_cache=use_cache, + pixel_values=pixel_values, + pixel_values_videos=pixel_values_videos, + image_grid_thw=image_grid_thw, + video_grid_thw=video_grid_thw, + input_features=input_features, + feature_attention_mask=feature_attention_mask, + use_audio_in_video=use_audio_in_video, + video_second_per_grid=video_second_per_grid, + is_first_iteration=is_first_iteration, + **kwargs, + ) + + model_inputs["position_ids"] = None + + if not is_first_iteration and use_cache: + model_inputs["pixel_values"] = None + model_inputs["pixel_values_videos"] = None + model_inputs["input_features"] = None + + return model_inputs + + +############################ +# Start Talker # +############################ + + +@dataclass +@auto_docstring( + custom_intro=""" + Base class for Qwen2.5OmniTalker causal language model (or autoregressive) outputs. + """ +) +class Qwen2_5OmniTalkerCausalLMOutputWithPast(ModelOutput): + r""" + loss (`torch.FloatTensor` of shape `(1,)`, *optional*, returned when `labels` is provided): + Language modeling loss (for next-token prediction). + logits (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.vocab_size)`): + Prediction scores of the language modeling head (scores for each vocabulary token before SoftMax). + past_key_values (`Cache`, *optional*, returned when `use_cache=True` is passed or when `config.use_cache=True`): + It is a [`~cache_utils.Cache`] instance. For more details, see our [kv cache guide](https://huggingface.co/docs/transformers/en/kv_cache). + + Contains pre-computed hidden-states (key and values in the self-attention blocks) that can be used (see + `past_key_values` input) to speed up sequential decoding. + rope_deltas (`torch.LongTensor` of shape `(batch_size, )`, *optional*): + The rope index difference between sequence length and multimodal rope. + thinker_reply_part (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`): + Hidden states from the thinker model that are used as input for the talker model. These represent the encoded + response that the talker model will use to generate speech tokens. + """ + + loss: torch.FloatTensor | None = None + logits: torch.FloatTensor | None = None + past_key_values: Cache | None = None + hidden_states: tuple[torch.FloatTensor] | None = None + attentions: tuple[torch.FloatTensor] | None = None + rope_deltas: torch.LongTensor | None = None + thinker_reply_part: torch.FloatTensor | None = None + + +class Qwen2_5OmniTalkerModel(Qwen2_5_VLTextModel): + config: Qwen2_5OmniTalkerConfig + input_modalities = ("image", "video", "audio", "text") + + _no_split_modules = ["Qwen2_5OmniTalkerDecoderLayer"] + + def __init__(self, config: Qwen2_5OmniTalkerConfig): + super().__init__(config) + self.embed_tokens = nn.Embedding(config.vocab_size, config.embedding_size, self.padding_idx) + + +class Qwen2_5OmniTalkerForConditionalGeneration(Qwen2_5OmniPreTrainedModelForConditionalGeneration, GenerationMixin): + config: Qwen2_5OmniTalkerConfig + base_model_prefix = "talker" + output_modalities = ("audio",) + + def __init__(self, config: Qwen2_5OmniTalkerConfig): + super().__init__(config) + + self.thinker_to_talker_proj = nn.Linear(config.embedding_size, config.hidden_size) + + self.model = Qwen2_5OmniTalkerModel(config) + self.codebook_size = config.vocab_size + self.codec_head = nn.Linear(config.hidden_size, self.codebook_size, bias=False) + + self.codec_bos_token = config.tts_codec_start_token_id + self.codec_eos_token = config.tts_codec_end_token_id + self.codec_pad_token = config.tts_codec_pad_token_id + self.codec_mask_token = config.tts_codec_mask_token_id + + self.text_bos_token = config.tts_text_start_token_id + self.text_eos_token = config.tts_text_end_token_id + self.text_pad_token = config.tts_text_pad_token_id + + self.spatial_merge_size = self.config.spatial_merge_size + self.rope_deltas = None + + self.post_init() + + def get_input_embeddings(self): + return self.model.get_input_embeddings() + + def set_input_embeddings(self, value): + self.model.set_input_embeddings(value) + + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.Tensor | None = None, + position_ids: torch.LongTensor | None = None, + past_key_values: Cache | None = None, + thinker_reply_part: torch.FloatTensor | None = None, + inputs_embeds: torch.FloatTensor | None = None, + rope_deltas: torch.LongTensor | None = None, + use_cache: bool | None = None, + cache_position: torch.LongTensor | None = None, + input_text_ids: torch.LongTensor | None = None, + image_grid_thw: torch.LongTensor | None = None, + video_grid_thw: torch.LongTensor | None = None, + use_audio_in_video: bool | None = None, + audio_feature_lengths: torch.LongTensor | None = None, + video_second_per_grid: torch.LongTensor | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + **kwargs, + ) -> tuple | Qwen2_5OmniTalkerCausalLMOutputWithPast: + r""" + thinker_reply_part (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*): + Hidden states from the thinker model's output that represent the text reply part to be processed. + rope_deltas (`torch.LongTensor` of shape `(batch_size, )`, *optional*): + The rope index difference between sequence length and multimodal rope. + input_text_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Input token IDs for text-only content, used for position calculation in multimodal contexts. + image_grid_thw (`torch.LongTensor` of shape `(num_images, 3)`, *optional*): + The temporal, height and width of feature shape of each image in LLM. + video_grid_thw (`torch.LongTensor` of shape `(num_videos, 3)`, *optional*): + The temporal, height and width of feature shape of each video in LLM. + use_audio_in_video (`bool`, *optional*): + Whether or not use audio track in video, should same as the parameter in `process_audio_info`. + audio_feature_lengths (`torch.LongTensor` of shape `(num_audios)`, *optional*): + The length of feature shape of each audio in LLM. + video_second_per_grid (`torch.LongTensor` of shape `(num_videos)`, *optional*): + Number of seconds per grid for each video, used for temporal feature mapping. + + Example: + + ```python + >>> from io import BytesIO + >>> from urllib.request import urlopen + >>> import librosa + >>> from transformers import AutoProcessor, Qwen2_5OmniTalkerForConditionalGeneration + + >>> model = Qwen2_5OmniTalkerForConditionalGeneration.from_pretrained("Qwen/Qwen2-Audio-7B") + >>> processor = AutoProcessor.from_pretrained("Qwen/Qwen2-Audio-7B") + + >>> prompt = "<|audio_bos|><|AUDIO|><|audio_eos|>Generate the caption in English:" + >>> url = "https://qianwen-res.oss-cn-beijing.aliyuncs.com/Qwen2-Audio/audio/glass-breaking-151256.mp3" + >>> audio, _ = librosa.load(BytesIO(urlopen(url).read()), sr=self.processor.feature_extractor.sampling_rate) + + >>> inputs = processor(text=prompt, audio=audio, return_tensors="pt") + + >>> # Generate + >>> generate_ids = model.generate(**inputs, max_length=30) + >>> processor.batch_decode(generate_ids, skip_special_tokens=True, clean_up_tokenization_spaces=False)[0] + "Generate the caption in English: Glass is breaking." + ```""" + + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + if attention_mask is not None and position_ids is None: + past_key_values_length = 0 if past_key_values is None else past_key_values.get_seq_length() + if past_key_values_length == 0 or self.rope_deltas is None: + position_ids, rope_deltas = self.get_rope_index( + input_text_ids, + image_grid_thw, + video_grid_thw, + attention_mask, + use_audio_in_video, + audio_feature_lengths, + video_second_per_grid, + ) + + if inputs_embeds is not None: + inputs_embeds[:, -1, :] += self.get_input_embeddings()( + torch.tensor([self.codec_bos_token], dtype=torch.long, device=inputs_embeds.device) + ) + inputs_embeds[:, -2, :] += self.get_input_embeddings()( + torch.tensor([self.codec_pad_token], dtype=torch.long, device=inputs_embeds.device) + ) + self.rope_deltas = rope_deltas + + else: + if inputs_embeds is not None: + batch_size, seq_length, _ = inputs_embeds.shape + else: + batch_size, seq_length = input_ids.shape + + delta = (past_key_values_length + self.rope_deltas).to(input_ids.device) + position_ids = torch.arange(seq_length, device=input_ids.device) + position_ids = position_ids.view(1, -1).expand(batch_size, -1) + position_ids = position_ids.add(delta) + position_ids = position_ids.unsqueeze(0).expand(3, -1, -1) + + if inputs_embeds is None: + # 1. Inference tokens after second token + codec_embeds = self.get_input_embeddings()(input_ids) + inputs_embeds = codec_embeds + thinker_reply_part[:, :1, :] + if thinker_reply_part.shape[1] > 1: + thinker_reply_part = thinker_reply_part[:, 1:, :] + + talker_lm_input = self.thinker_to_talker_proj(inputs_embeds) + + if attention_mask is not None: + attention_mask = attention_mask.to(inputs_embeds.device) + + outputs = self.model( + attention_mask=attention_mask, + position_ids=position_ids, + past_key_values=past_key_values, + inputs_embeds=talker_lm_input, + use_cache=use_cache, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + + hidden_states = outputs[0] + logits = self.codec_head(hidden_states) + logits = logits.float() + + loss = None + + if not return_dict: + output = (logits,) + outputs[1:] + return (loss,) + output if loss is not None else output + + return Qwen2_5OmniTalkerCausalLMOutputWithPast( + loss=loss, + logits=logits, + past_key_values=outputs.past_key_values, + hidden_states=hidden_states, + attentions=outputs.attentions, + rope_deltas=self.rope_deltas, + thinker_reply_part=thinker_reply_part, + ) + + def _get_initial_cache_position(self, seq_length, device, model_kwargs): + # Talker needs to calculate cache_position with input_ids, so pop inputs_embeds temporarily + inputs_embeds = model_kwargs.pop("inputs_embeds") + model_kwargs = super()._get_initial_cache_position(seq_length, device, model_kwargs) + model_kwargs["inputs_embeds"] = inputs_embeds + return model_kwargs + + # prepare inputs for talker lm generation + def prepare_inputs_for_generation( + self, + input_ids, + input_text_ids, + past_key_values=None, + attention_mask=None, + inputs_embeds=None, + thinker_reply_part=None, + cache_position=None, + position_ids=None, + use_cache=True, + pixel_values=None, + pixel_values_videos=None, + image_grid_thw=None, + video_grid_thw=None, + input_audio_features=None, + audio_feature_attention_mask=None, + audio_feature_lengths=None, + use_audio_in_video=False, + video_second_per_grid=None, + **kwargs, + ): + model_inputs = super().prepare_inputs_for_generation( + input_ids, + past_key_values, + attention_mask, + inputs_embeds, + cache_position, + use_cache=use_cache, + thinker_reply_part=thinker_reply_part, + input_text_ids=input_text_ids, + image_grid_thw=image_grid_thw, + video_grid_thw=video_grid_thw, + use_audio_in_video=use_audio_in_video, + audio_feature_lengths=audio_feature_lengths, + video_second_per_grid=video_second_per_grid, + **kwargs, + ) + + model_inputs["position_ids"] = None + + return model_inputs + + def _update_model_kwargs_for_generation( + self, + outputs: ModelOutput, + model_kwargs: dict[str, Any], + is_encoder_decoder: bool = False, + num_new_tokens: int = 1, + ) -> dict[str, Any]: + model_kwargs = super()._update_model_kwargs_for_generation( + outputs, model_kwargs, is_encoder_decoder, num_new_tokens + ) + + if getattr(outputs, "thinker_reply_part", None) is not None: + model_kwargs["thinker_reply_part"] = outputs.thinker_reply_part + + return model_kwargs + + +############################ +# Start Token2Wav # +############################ + + +class Qwen2_5OmniDiTRotaryEmbedding(LlamaRotaryEmbedding): + def __init__(self, config: Qwen2_5OmniDiTConfig, device=None): + super().__init__(config, device=device) + + @staticmethod + def compute_default_rope_parameters( + config: Qwen2_5OmniDiTConfig | None = None, + device: Optional["torch.device"] = None, + seq_len: int | None = None, + ) -> tuple["torch.Tensor", float]: + return super().compute_default_rope_parameters( + config, + device=device, + seq_len=seq_len, + ) + + +# Modified from Llama with a different rotate function, will fixed in next release +def apply_rotary_pos_emb(q, k, cos, sin, unsqueeze_dim=1): + """Applies Rotary Position Embedding to the query and key tensors. + + Args: + q (`torch.Tensor`): The query tensor. + k (`torch.Tensor`): The key tensor. + cos (`torch.Tensor`): The cosine part of the rotary embedding. + sin (`torch.Tensor`): The sine part of the rotary embedding. + unsqueeze_dim (`int`, *optional*, defaults to 1): + The 'unsqueeze_dim' argument specifies the dimension along which to unsqueeze cos[position_ids] and + sin[position_ids] so that they can be properly broadcasted to the dimensions of q and k. For example, note + that cos[position_ids] and sin[position_ids] have the shape [batch_size, seq_len, head_dim]. Then, if q and + k have the shape [batch_size, heads, seq_len, head_dim], then setting unsqueeze_dim=1 makes + cos[position_ids] and sin[position_ids] broadcastable to the shapes of q and k. Similarly, if q and k have + the shape [batch_size, seq_len, heads, head_dim], then set unsqueeze_dim=2. + Returns: + `tuple(torch.Tensor)` comprising of the query and key tensors rotated using the Rotary Position Embedding. + """ + + def rotate_half_codec(x): + # x = rearrange(x, "... (d r) -> ... d r", r=2) + x = x.reshape(*x.shape[:-1], -1, 2) + x1, x2 = x.unbind(dim=-1) + x = torch.stack((-x2, x1), dim=-1) + return x.reshape(*x.shape[:-2], -1) + + cos = cos.unsqueeze(unsqueeze_dim) + sin = sin.unsqueeze(unsqueeze_dim) + q_embed = (q * cos) + (rotate_half_codec(q) * sin) + k_embed = (k * cos) + (rotate_half_codec(k) * sin) + return q_embed, k_embed + + +class TimeDelayNetBlock(nn.Module): + def __init__( + self, + in_channels, + out_channels, + kernel_size, + dilation, + ): + super().__init__() + self.conv = nn.Conv1d( + in_channels=in_channels, + out_channels=out_channels, + kernel_size=kernel_size, + dilation=dilation, + padding="same", + padding_mode="reflect", + ) + self.activation = nn.ReLU() + + def forward(self, hidden_states: torch.Tensor): + return self.activation(self.conv(hidden_states)) + + +class Res2NetBlock(torch.nn.Module): + def __init__(self, in_channels, out_channels, scale=8, kernel_size=3, dilation=1): + super().__init__() + + in_channel = in_channels // scale + hidden_channel = out_channels // scale + + self.blocks = nn.ModuleList( + [ + TimeDelayNetBlock( + in_channel, + hidden_channel, + kernel_size=kernel_size, + dilation=dilation, + ) + for i in range(scale - 1) + ] + ) + self.scale = scale + + def forward(self, hidden_states): + outputs = [] + for i, hidden_part in enumerate(torch.chunk(hidden_states, self.scale, dim=1)): + if i == 0: + output_part = hidden_part + elif i == 1: + output_part = self.blocks[i - 1](hidden_part) + else: + output_part = self.blocks[i - 1](hidden_part + output_part) + outputs.append(output_part) + output = torch.cat(outputs, dim=1) + return output + + +class SqueezeExcitationBlock(nn.Module): + def __init__(self, in_channels, se_channels, out_channels): + super().__init__() + + self.conv1 = nn.Conv1d( + in_channels=in_channels, + out_channels=se_channels, + kernel_size=1, + padding="same", + padding_mode="reflect", + ) + self.relu = nn.ReLU(inplace=True) + self.conv2 = nn.Conv1d( + in_channels=se_channels, + out_channels=out_channels, + kernel_size=1, + padding="same", + padding_mode="reflect", + ) + self.sigmoid = nn.Sigmoid() + + def forward(self, hidden_states): + hidden_states_mean = hidden_states.mean(dim=2, keepdim=True) + + hidden_states_mean = self.relu(self.conv1(hidden_states_mean)) + hidden_states_mean = self.sigmoid(self.conv2(hidden_states_mean)) + + return hidden_states * hidden_states_mean + + +class AttentiveStatisticsPooling(nn.Module): + """This class implements an attentive statistic pooling layer for each channel. + It returns the concatenated mean and std of the input tensor. + """ + + def __init__(self, channels, attention_channels=128): + super().__init__() + + self.eps = 1e-12 + self.tdnn = TimeDelayNetBlock(channels * 3, attention_channels, 1, 1) + self.tanh = nn.Tanh() + self.conv = nn.Conv1d( + in_channels=attention_channels, + out_channels=channels, + kernel_size=1, + padding="same", + padding_mode="reflect", + ) + + def _length_to_mask(self, length, max_len=None, dtype=None, device=None): + """Creates a binary mask for each sequence. + + Reference: https://discuss.pytorch.org/t/how-to-generate-variable-length-mask/23397/3 + + Arguments + --------- + length : torch.LongTensor + Containing the length of each sequence in the batch. Must be 1D. + max_len : int + Max length for the mask, also the size of the second dimension. + dtype : torch.dtype, default: None + The dtype of the generated mask. + device: torch.device, default: None + The device to put the mask variable. + + Returns + ------- + mask : tensor + The binary mask. + """ + + if max_len is None: + max_len = length.max().long().item() # using arange to generate mask + mask = torch.arange(max_len, device=length.device, dtype=length.dtype).expand( + len(length), max_len + ) < length.unsqueeze(1) + + mask = torch.as_tensor(mask, dtype=dtype, device=device) + return mask + + def _compute_statistics(self, x, m, dim=2): + mean = (m * x).sum(dim) + std = torch.sqrt((m * (x - mean.unsqueeze(dim)).pow(2)).sum(dim).clamp(self.eps)) + return mean, std + + def forward(self, hidden_states): + seq_length = hidden_states.shape[-1] + lengths = torch.ones(hidden_states.shape[0], device=hidden_states.device) + + # Make binary mask of shape [N, 1, L] + mask = self._length_to_mask( + lengths * seq_length, max_len=seq_length, dtype=hidden_states.dtype, device=hidden_states.device + ) + mask = mask.unsqueeze(1) + + # Expand the temporal context of the pooling layer by allowing the + # self-attention to look at global properties of the utterance. + total = mask.sum(dim=2, keepdim=True) + + mean, std = self._compute_statistics(hidden_states, mask / total) + mean = mean.unsqueeze(2).repeat(1, 1, seq_length) + std = std.unsqueeze(2).repeat(1, 1, seq_length) + attention = torch.cat([hidden_states, mean, std], dim=1) + + # Apply layers + attention = self.conv(self.tanh(self.tdnn(attention))) + + # Filter out zero-paddings + attention = attention.masked_fill(mask == 0, float("-inf")) + + attention = F.softmax(attention, dim=2) + mean, std = self._compute_statistics(hidden_states, attention) + # Append mean and std of the batch + pooled_stats = torch.cat((mean, std), dim=1) + pooled_stats = pooled_stats.unsqueeze(2) + + return pooled_stats + + +class SqueezeExcitationRes2NetBlock(nn.Module): + """An implementation of building block in ECAPA-TDNN, i.e., + TDNN-Res2Net-TDNN-SqueezeExcitationBlock. + """ + + def __init__( + self, + in_channels, + out_channels, + res2net_scale=8, + se_channels=128, + kernel_size=1, + dilation=1, + ): + super().__init__() + self.out_channels = out_channels + self.tdnn1 = TimeDelayNetBlock( + in_channels, + out_channels, + kernel_size=1, + dilation=1, + ) + self.res2net_block = Res2NetBlock(out_channels, out_channels, res2net_scale, kernel_size, dilation) + self.tdnn2 = TimeDelayNetBlock( + out_channels, + out_channels, + kernel_size=1, + dilation=1, + ) + self.se_block = SqueezeExcitationBlock(out_channels, se_channels, out_channels) + + def forward(self, hidden_state): + residual = hidden_state + + hidden_state = self.tdnn1(hidden_state) + hidden_state = self.res2net_block(hidden_state) + hidden_state = self.tdnn2(hidden_state) + hidden_state = self.se_block(hidden_state) + + return hidden_state + residual + + +class ECAPA_TimeDelayNet(torch.nn.Module): + """An implementation of the speaker embedding model in a paper. + "ECAPA-TDNN: Emphasized Channel Attention, Propagation and Aggregation in + TDNN Based Speaker Verification" (https://huggingface.co/papers/2005.07143). + """ + + def __init__(self, config: Qwen2_5OmniDiTConfig): + super().__init__() + if len(config.enc_channels) != len(config.enc_kernel_sizes) or len(config.enc_channels) != len( + config.enc_dilations + ): + raise ValueError("enc_channels, enc_kernel_sizes and enc_dilations should have same length") + self.channels = config.enc_channels + self.blocks = nn.ModuleList() + + # The initial TDNN layer + self.blocks.append( + TimeDelayNetBlock( + config.mel_dim, + config.enc_channels[0], + config.enc_kernel_sizes[0], + config.enc_dilations[0], + ) + ) + + # SE-Res2Net layers + for i in range(1, len(config.enc_channels) - 1): + self.blocks.append( + SqueezeExcitationRes2NetBlock( + config.enc_channels[i - 1], + config.enc_channels[i], + res2net_scale=config.enc_res2net_scale, + se_channels=config.enc_se_channels, + kernel_size=config.enc_kernel_sizes[i], + dilation=config.enc_dilations[i], + ) + ) + + # Multi-layer feature aggregation + self.mfa = TimeDelayNetBlock( + config.enc_channels[-1], + config.enc_channels[-1], + config.enc_kernel_sizes[-1], + config.enc_dilations[-1], + ) + + # Attentive Statistical Pooling + self.asp = AttentiveStatisticsPooling( + config.enc_channels[-1], + attention_channels=config.enc_attention_channels, + ) + + # Final linear transformation + self.fc = nn.Conv1d( + in_channels=config.enc_channels[-1] * 2, + out_channels=config.enc_dim, + kernel_size=1, + padding="same", + padding_mode="reflect", + ) + + def forward(self, hidden_states): + # Minimize transpose for efficiency + hidden_states = hidden_states.transpose(1, 2) + + hidden_states_list = [] + for layer in self.blocks: + hidden_states = layer(hidden_states) + hidden_states_list.append(hidden_states) + + # Multi-layer feature aggregation + hidden_states = torch.cat(hidden_states_list[1:], dim=1) + hidden_states = self.mfa(hidden_states) + + # Attentive Statistical Pooling + hidden_states = self.asp(hidden_states) + + # Final linear transformation + hidden_states = self.fc(hidden_states) + + hidden_states = hidden_states.squeeze(-1) + return hidden_states + + +class DiTInputEmbedding(nn.Module): + def __init__(self, config: Qwen2_5OmniDiTConfig): + super().__init__() + self.proj = nn.Linear( + config.mel_dim + config.enc_dim + config.enc_emb_dim + config.emb_dim, + config.hidden_size, + ) + self.spk_encoder = ECAPA_TimeDelayNet(config) + + def forward( + self, + hidden_states: torch.Tensor, + speaker_embedding: torch.Tensor, + condition_vector: torch.Tensor, + code_embed: torch.Tensor, + drop_audio_cond: bool | None = False, + code_embed_uncond: bool | None = None, + apply_cfg: bool | None = True, + ): + if apply_cfg: + hidden_states = torch.cat([hidden_states, hidden_states], dim=0) + speaker_embedding = torch.cat([speaker_embedding, torch.zeros_like(speaker_embedding)], dim=0) + condition_vector = torch.cat([condition_vector, torch.zeros_like(condition_vector)], dim=0) + code_embed = torch.cat([code_embed, code_embed_uncond], dim=0) + elif drop_audio_cond: # cfg for cond audio + condition_vector = torch.zeros_like(condition_vector) + speaker_embedding = torch.zeros_like(speaker_embedding) + condition_vector = self.spk_encoder(condition_vector).unsqueeze(1).repeat(1, hidden_states.size(1), 1) + hidden_states = self.proj(torch.cat((hidden_states, condition_vector, code_embed, speaker_embedding), dim=-1)) + + return hidden_states + + +# Transformer backbone using DiT blocks +class DiTCodecEmbedding(nn.Module): + def __init__(self, codec_num_embeds, codec_dim, repeats): + super().__init__() + self.repeats = repeats + self.codec_embed = nn.Embedding(codec_num_embeds + 1, codec_dim) + + def forward(self, code, drop_code=False): + if drop_code: + code = torch.zeros_like(code) + code_embed = self.codec_embed(code) + + code_embed = torch.repeat_interleave(code_embed, repeats=self.repeats, dim=1) + return code_embed + + +# AdaLayerNormZero +# return with modulated x for attn input, and params for later mlp modulation +class Qwen2_5_OmniAdaLayerNormZero(nn.Module): + def __init__(self, dim): + super().__init__() + + self.silu = nn.SiLU() + self.linear = nn.Linear(dim, dim * 6) + + self.norm = nn.LayerNorm(dim, elementwise_affine=False, eps=1e-6) + + def forward(self, hidden_states, emb=None): + emb = self.linear(self.silu(emb)) + shift_msa, scale_msa, gate_msa, shift_mlp, scale_mlp, gate_mlp = torch.chunk(emb, 6, dim=1) + + hidden_states = self.norm(hidden_states) * (1 + scale_msa[:, None]) + shift_msa[:, None] + return hidden_states, gate_msa, shift_mlp, scale_mlp, gate_mlp + + +# AdaLayerNormZero for final layer +# return only with modulated x for attn input, cuz no more mlp modulation +class Qwen2_5_OmniAdaLayerNormZero_Final(nn.Module): + def __init__(self, dim): + super().__init__() + + self.silu = nn.SiLU() + self.linear = nn.Linear(dim, dim * 2) + + self.norm = nn.LayerNorm(dim, elementwise_affine=False, eps=1e-6) + + def forward(self, hidden_states, emb): + emb = self.linear(self.silu(emb)) + scale, shift = torch.chunk(emb, 2, dim=1) + + hidden_states = self.norm(hidden_states) * (1 + scale)[:, None, :] + shift[:, None, :] + return hidden_states + + +# FeedForward +class DiTMLP(nn.Module): + def __init__(self, dim, mult=4, dropout=0.0): + super().__init__() + inner_dim = int(dim * mult) + + self.ff = nn.ModuleList( + [ + nn.Linear(dim, inner_dim), + nn.GELU(approximate="tanh"), + nn.Dropout(dropout), + nn.Linear(inner_dim, dim), + ] + ) + + def forward(self, hidden_states): + for layer in self.ff: + hidden_states = layer(hidden_states) + return hidden_states + + +class DiTAttention(nn.Module): + def __init__(self, config: Qwen2_5OmniDiTConfig): + super().__init__() + + self.config = config + self.dim = config.hidden_size + self.heads = config.num_attention_heads + self.inner_dim = config.head_dim * config.num_attention_heads + self.dropout = config.dropout + self.is_causal = False + + self.to_q = nn.Linear(config.hidden_size, self.inner_dim) + self.to_k = nn.Linear(config.hidden_size, self.inner_dim) + self.to_v = nn.Linear(config.hidden_size, self.inner_dim) + + self.to_out = nn.ModuleList([nn.Linear(self.inner_dim, config.hidden_size), nn.Dropout(config.dropout)]) + + def forward( + self, + hidden_states, # noised input x + position_embeddings=None, # rotary position embedding for x + attention_mask=None, + ) -> torch.Tensor: + batch_size = hidden_states.shape[0] + + # `sample` projections. + query = self.to_q(hidden_states) + key = self.to_k(hidden_states) + value = self.to_v(hidden_states) + + # attention + inner_dim = key.shape[-1] + head_dim = inner_dim // self.heads + query = query.view(batch_size, -1, self.heads, head_dim).transpose(1, 2) + key = key.view(batch_size, -1, self.heads, head_dim).transpose(1, 2) + value = value.view(batch_size, -1, self.heads, head_dim).transpose(1, 2) + + # apply rotary position embedding + # Due to training process, only first head is applied with RoPE, will be fixed at next release + cos, sin = position_embeddings + query[:, :1], key[:, :1] = apply_rotary_pos_emb(query[:, :1], key[:, :1], cos, sin) + + attention_interface = ALL_ATTENTION_FUNCTIONS[self.config._attn_implementation] + attention_weights, _ = attention_interface( + self, + query, + key, + value, + attention_mask=attention_mask, + is_causal=False, + ) + + # mask. e.g. inference got a batch with different target durations, mask out the padding + attention_weights = attention_weights.reshape(batch_size, -1, self.heads * head_dim) + attention_weights = attention_weights.to(query.dtype) + + # linear proj + attention_output = self.to_out[0](attention_weights) + attention_output = self.to_out[1](attention_output) + + return attention_output + + +# time step conditioning embedding +class SinusPositionEmbedding(nn.Module): + def __init__(self, dim): + super().__init__() + self.dim = dim + + def forward(self, hidden_states, scale=1000): + device = hidden_states.device + half_dim = self.dim // 2 + emb = math.log(10000) / (half_dim - 1) + emb = torch.exp(torch.arange(half_dim, device=device).float() * -emb) + emb = scale * hidden_states.unsqueeze(1) * emb.unsqueeze(0) + emb = torch.cat((emb.sin(), emb.cos()), dim=-1) + return emb.type_as(hidden_states) + + +class DiTTimestepEmbedding(nn.Module): + def __init__(self, dim, freq_embed_dim=256): + super().__init__() + self.time_embed = SinusPositionEmbedding(freq_embed_dim) + self.time_mlp = nn.ModuleList([nn.Linear(freq_embed_dim, dim), nn.SiLU(), nn.Linear(dim, dim)]) + + def forward(self, timestep): + time_hidden = self.time_embed(timestep) + time_hidden = time_hidden.to(timestep.dtype) + for layer in self.time_mlp: + time_hidden = layer(time_hidden) # b d + return time_hidden + + +class DiTDecoderLayer(nn.Module): + def __init__(self, config: Qwen2_5OmniDiTConfig, look_ahead_block=0, look_backward_block=0): + super().__init__() + self.attn_norm = Qwen2_5_OmniAdaLayerNormZero(config.hidden_size) + + self.attn = DiTAttention(config) + self.look_ahead_block = look_ahead_block + self.look_backward_block = look_backward_block + self.ff_norm = nn.LayerNorm(config.hidden_size, elementwise_affine=False, eps=1e-6) + self.ff = DiTMLP(dim=config.hidden_size, mult=config.ff_mult, dropout=config.dropout) + + def forward( + self, hidden_states, timestep, position_embeddings=None, block_diff=None + ): # x: noised input, t: time embedding + # pre-norm & modulation for attention input + norm, gate_msa, shift_mlp, scale_mlp, gate_mlp = self.attn_norm(hidden_states, emb=timestep) + + # attention + attn_output = self.attn( + hidden_states=norm, + position_embeddings=position_embeddings, + attention_mask=(block_diff >= -float(self.look_backward_block)) + & (block_diff <= float(self.look_ahead_block)), + ) + + # process attention output for input x + hidden_states = hidden_states + gate_msa.unsqueeze(1) * attn_output + + norm = self.ff_norm(hidden_states) * (1 + scale_mlp[:, None]) + shift_mlp[:, None] + ff_output = self.ff(norm) + hidden_states = hidden_states + gate_mlp.unsqueeze(1) * ff_output + + return hidden_states + + +class SnakeBeta(nn.Module): + """ + A modified Snake function which uses separate parameters for the magnitude of the periodic components + Shape: + - Input: (B, C, T) + - Output: (B, C, T), same shape as the input + Parameters: + - alpha - trainable parameter that controls frequency + - beta - trainable parameter that controls magnitude + References: + - This activation function is a modified version based on this paper by Liu Ziyin, Tilman Hartwig, Masahito Ueda: + https://huggingface.co/papers/2006.08195 + """ + + def __init__(self, in_features, alpha=1.0): + super().__init__() + self.in_features = in_features + + # initialize alpha + self.alpha = Parameter(torch.zeros(in_features) * alpha) + self.beta = Parameter(torch.zeros(in_features) * alpha) + + self.no_div_by_zero = 0.000000001 + + def forward(self, hidden_states): + """ + Forward pass of the function. + Applies the function to the input elementwise. + SnakeBeta ∶= x + 1/b * sin^2 (xa) + """ + alpha = self.alpha.unsqueeze(0).unsqueeze(-1) # line up with x to [B, C, T] + beta = self.beta.unsqueeze(0).unsqueeze(-1) + alpha = torch.exp(alpha) + beta = torch.exp(beta) + hidden_states = hidden_states + (1.0 / (beta + self.no_div_by_zero)) * torch.pow( + torch.sin(hidden_states * alpha), 2 + ) + + return hidden_states + + +def kaiser_sinc_filter1d(cutoff, half_width, kernel_size): + """Generates a 1D Kaiser-windowed sinc filter. + + Args: + cutoff (float): Normalized cutoff frequency (0 to 0.5). + half_width (float): Transition bandwidth. + kernel_size (int): Number of filter taps. + + Returns: + torch.Tensor: A tensor of shape (1, 1, kernel_size) representing the filter. + """ + is_even = kernel_size % 2 == 0 + half_size = kernel_size // 2 + + # Compute Kaiser window parameters + delta_f = 4 * half_width + attenuation = 2.285 * (half_size - 1) * math.pi * delta_f + 7.95 + + if attenuation > 50.0: + beta = 0.1102 * (attenuation - 8.7) + elif attenuation >= 21.0: + beta = 0.5842 * (attenuation - 21) ** 0.4 + 0.07886 * (attenuation - 21.0) + else: + beta = 0.0 + + kaiser_window = torch.kaiser_window(kernel_size, beta=beta, periodic=False, dtype=torch.float32) + + # Compute time indices + if is_even: + time_indices = torch.arange(-half_size, half_size) + 0.5 + else: + time_indices = torch.arange(kernel_size) - half_size + + # Compute sinc filter + if cutoff == 0: + return torch.zeros((1, 1, kernel_size), dtype=torch.float32) # Ensures correct shape + + sinc_filter = torch.sinc(2 * cutoff * time_indices) + normalized_filter = 2 * cutoff * kaiser_window * sinc_filter + + # Normalize to ensure sum = 1 (avoid leakage of constant component) + normalized_filter /= normalized_filter.sum() + + return normalized_filter.view(1, 1, kernel_size) + + +class UpSample1d(nn.Module): + def __init__(self, ratio=2, kernel_size=None): + super().__init__() + self.ratio = ratio + self.kernel_size = int(6 * ratio // 2) * 2 if kernel_size is None else kernel_size + self.stride = ratio + self.pad = self.kernel_size // ratio - 1 + self.pad_left = self.pad * self.stride + (self.kernel_size - self.stride) // 2 + self.pad_right = self.pad * self.stride + (self.kernel_size - self.stride + 1) // 2 + + filter = kaiser_sinc_filter1d(cutoff=0.5 / ratio, half_width=0.6 / ratio, kernel_size=self.kernel_size) + self.register_buffer("filter", filter, persistent=False) + + def forward(self, hidden_states): + channels = hidden_states.shape[1] + + hidden_states = F.pad(hidden_states, (self.pad, self.pad), mode="replicate") + hidden_states = self.ratio * F.conv_transpose1d( + hidden_states, self.filter.expand(channels, -1, -1), stride=self.stride, groups=channels + ) + hidden_states = hidden_states[..., self.pad_left : -self.pad_right] + + return hidden_states + + +class DownSample1d(nn.Module): + def __init__(self, ratio=2, kernel_size=None): + super().__init__() + cutoff = 0.5 / ratio + half_width = 0.6 / ratio + self.cutoff = cutoff + self.half_width = half_width + self.kernel_size = kernel_size + + if cutoff < 0.0: + raise ValueError("Minimum cutoff must be larger than zero.") + if cutoff > 0.5: + raise ValueError("A cutoff above 0.5 does not make sense.") + + self.even = kernel_size % 2 == 0 + self.pad_left = kernel_size // 2 - int(self.even) + self.pad_right = kernel_size // 2 + self.stride = ratio + filter = kaiser_sinc_filter1d(cutoff, half_width, kernel_size) + self.register_buffer("filter", filter, persistent=False) + + def forward(self, hidden_states): + channels = hidden_states.shape[1] + hidden_states = F.pad(hidden_states, (self.pad_left, self.pad_right), mode="replicate") + out = F.conv1d(hidden_states, self.filter.expand(channels, -1, -1), stride=self.stride, groups=channels) + return out + + +class TorchActivation1d(nn.Module): + def __init__( + self, + activation, + up_ratio: int = 2, + down_ratio: int = 2, + up_kernel_size: int = 12, + down_kernel_size: int = 12, + ): + super().__init__() + if not callable(activation): + raise TypeError("Activation function must be callable") + self.act = activation + self.upsample = UpSample1d(up_ratio, up_kernel_size) + self.downsample = DownSample1d(down_ratio, down_kernel_size) + + def forward(self, hidden_states): + hidden_states = self.upsample(hidden_states) + hidden_states = self.act(hidden_states) + hidden_states = self.downsample(hidden_states) + + return hidden_states + + +class AMPBlock(torch.nn.Module): + def __init__( + self, + channels, + kernel_size=3, + dilation=(1, 3, 5), + ): + super().__init__() + + self.convs1 = nn.ModuleList( + [ + nn.Conv1d( + channels, + channels, + kernel_size, + 1, + dilation=dilation[0], + padding=self._get_padding(kernel_size, dilation[0]), + ), + nn.Conv1d( + channels, + channels, + kernel_size, + 1, + dilation=dilation[1], + padding=self._get_padding(kernel_size, dilation[1]), + ), + nn.Conv1d( + channels, + channels, + kernel_size, + 1, + dilation=dilation[2], + padding=self._get_padding(kernel_size, dilation[2]), + ), + ] + ) + + self.convs2 = nn.ModuleList( + [ + nn.Conv1d( + channels, + channels, + kernel_size, + 1, + dilation=1, + padding=self._get_padding(kernel_size, 1), + ), + nn.Conv1d( + channels, + channels, + kernel_size, + 1, + dilation=1, + padding=self._get_padding(kernel_size, 1), + ), + nn.Conv1d( + channels, + channels, + kernel_size, + 1, + dilation=1, + padding=self._get_padding(kernel_size, 1), + ), + ] + ) + + self.num_layers = len(self.convs1) + len(self.convs2) # total number of conv layers + + self.activations = nn.ModuleList( + [TorchActivation1d(activation=SnakeBeta(channels)) for _ in range(self.num_layers)] + ) + + def _get_padding(self, kernel_size, dilation=1): + return int((kernel_size * dilation - dilation) / 2) + + def forward(self, hidden_states): + acts1, acts2 = self.activations[::2], self.activations[1::2] + for conv1, conv2, act1, act2 in zip(self.convs1, self.convs2, acts1, acts2): + residual = hidden_states + hidden_states = act1(hidden_states) + hidden_states = conv1(hidden_states) + hidden_states = act2(hidden_states) + hidden_states = conv2(hidden_states) + hidden_states = residual + hidden_states + + return hidden_states + + +@auto_docstring( + custom_intro=""" + The full Qwen2.5Omni Token2WavBigVGAN model. Which take mel spectrogram as input and predict waveform. + """ +) +class Qwen2_5OmniToken2WavBigVGANModel(Qwen2_5OmniPreTrainedModel): + config: Qwen2_5OmniBigVGANConfig + input_modalities = "audio" + + def __init__(self, config: Qwen2_5OmniBigVGANConfig): + super().__init__(config) + self.num_residual_blocks = len(config.resblock_kernel_sizes) + self.num_upsample_layers = len(config.upsample_rates) + + self.conv_pre = nn.Conv1d(config.mel_dim, config.upsample_initial_channel, 7, 1, padding=3) + + # Removing extra ModuleList breaks official state dict + ups = [ + nn.ModuleList( + [ + nn.ConvTranspose1d( + config.upsample_initial_channel // (2**layer_idx), + config.upsample_initial_channel // (2 ** (layer_idx + 1)), + kernel_size, + stride, + padding=(kernel_size - stride) // 2, + ) + ] + ) + for layer_idx, (stride, kernel_size) in enumerate(zip(config.upsample_rates, config.upsample_kernel_sizes)) + ] + self.ups = nn.ModuleList(ups) + + self.resblocks = nn.ModuleList( + [ + AMPBlock(config.upsample_initial_channel // (2 ** (layer_idx + 1)), kernel_size, dilation) + for layer_idx in range(self.num_upsample_layers) + for kernel_size, dilation in zip(config.resblock_kernel_sizes, config.resblock_dilation_sizes) + ] + ) + + self.activation_post = TorchActivation1d( + activation=SnakeBeta(config.upsample_initial_channel // (2**self.num_upsample_layers)) + ) + self.conv_post = nn.Conv1d( + config.upsample_initial_channel // (2**self.num_upsample_layers), 1, 7, 1, padding=3, bias=False + ) + + self.post_init() + + def normalize_spectrogram(self, spectrogram, max_value, min_db): + return torch.clamp((2 * max_value) * ((spectrogram - min_db) / (-min_db)) - max_value, -max_value, max_value) + + def amplitude_to_db(self, amplitude, min_db_level): + min_level = torch.exp( + torch.tensor(min_db_level / 20.0 * np.log(10), device=amplitude.device, dtype=amplitude.dtype) + ) + return 20 * torch.log10(torch.clamp(amplitude, min=min_level)) + + def process_mel_spectrogram(self, mel_spectrogram): + amplitude_spectrum = torch.exp(mel_spectrogram) + decibel_spectrum = self.amplitude_to_db(amplitude_spectrum, -115) - 20 + return self.normalize_spectrogram(decibel_spectrum, 1, -115) + + def forward(self, mel_spectrogram, **kwargs): + processed_spectrogram = self.process_mel_spectrogram(mel_spectrogram) + hidden_representation = self.conv_pre(processed_spectrogram) + + for layer_index in range(self.num_upsample_layers): + hidden_representation = self.ups[layer_index][0](hidden_representation) + residual_output = sum( + self.resblocks[layer_index * self.num_residual_blocks + block_index](hidden_representation) + for block_index in range(self.num_residual_blocks) + ) + residual_output = residual_output / self.num_residual_blocks + hidden_representation = residual_output + + hidden_representation = self.activation_post(hidden_representation) + output_waveform = self.conv_post(hidden_representation) + return torch.clamp(output_waveform, min=-1.0, max=1.0).squeeze().cpu() + + +class RungeKutta4ODESolver: + def __init__(self, function, initial_value): + self.function = function + self.initial_value = initial_value + + self._one_third = 1 / 3 + self._two_thirds = 2 / 3 + + def _rk4_step(self, function, time_start, time_step, time_end, value_start, function_value_start=None): + k1 = function_value_start if function_value_start is not None else function(time_start, value_start) + k2 = function(time_start + time_step * self._one_third, value_start + time_step * k1 * self._one_third) + k3 = function(time_start + time_step * self._two_thirds, value_start + time_step * (k2 - k1 * self._one_third)) + k4 = function(time_end, value_start + time_step * (k1 - k2 + k3)) + return (k1 + 3 * (k2 + k3) + k4) * time_step / 8 + + def _compute_step(self, function, time_start, time_step, time_end, value_start): + function_value_start = function(time_start, value_start) + return self._rk4_step( + function, time_start, time_step, time_end, value_start, function_value_start=function_value_start + ), function_value_start + + def _linear_interpolation(self, time_start, time_end, value_start, value_end, time_point): + if time_point == time_start: + return value_start + if time_point == time_end: + return value_end + weight = (time_point - time_start) / (time_end - time_start) + return value_start + weight * (value_end - value_start) + + def integrate(self, time_points): + solution = torch.empty( + len(time_points), + *self.initial_value.shape, + dtype=self.initial_value.dtype, + device=self.initial_value.device, + ) + solution[0] = self.initial_value + + current_index = 1 + current_value = self.initial_value + for time_start, time_end in zip(time_points[:-1], time_points[1:]): + time_step = time_end - time_start + delta_value, _ = self._compute_step(self.function, time_start, time_step, time_end, current_value) + next_value = current_value + delta_value + + while current_index < len(time_points) and time_end >= time_points[current_index]: + solution[current_index] = self._linear_interpolation( + time_start, time_end, current_value, next_value, time_points[current_index] + ) + current_index += 1 + + current_value = next_value + + return solution + + +@auto_docstring( + custom_intro=""" + The full Qwen2.5Omni Token2WavDiT model. Which take speech tokens as input and predict mel spectrogram. + """ +) +class Qwen2_5OmniToken2WavDiTModel(Qwen2_5OmniPreTrainedModel): + config: Qwen2_5OmniDiTConfig + input_modalities = "audio" + _no_split_modules = ["DiTDecoderLayer"] + + def __init__(self, config: Qwen2_5OmniDiTConfig): + super().__init__(config) + self.mel_dim = config.mel_dim + self.repeats = config.repeats + self.time_embed = DiTTimestepEmbedding(config.hidden_size) + + self.text_embed = DiTCodecEmbedding(config.num_embeds, config.emb_dim, config.repeats) + self.input_embed = DiTInputEmbedding(config) + + self.rotary_embed = Qwen2_5OmniDiTRotaryEmbedding(config=config) + + self.hidden_size = config.hidden_size + self.layers = config.num_hidden_layers + self.block_size = config.block_size + self.num_attention_heads = config.num_attention_heads + + self.transformer_blocks = nn.ModuleList() + for i in range(config.num_hidden_layers): + self.transformer_blocks.append( + DiTDecoderLayer( + config, + look_ahead_block=1 if i in config.look_ahead_layers else 0, + look_backward_block=1 if i in config.look_backward_layers else 0, + ) + ) + + self.norm_out = Qwen2_5_OmniAdaLayerNormZero_Final(config.hidden_size) # final modulation + self.proj_out = nn.Linear(config.hidden_size, config.mel_dim) + + self.post_init() + + def _create_block_diff(self, hidden_states): + batch, seq_len = hidden_states.shape[0], hidden_states.shape[1] + block_indices = torch.arange(seq_len, device=hidden_states.device) // self.block_size # [seq_length] + + block_i = block_indices.unsqueeze(1) # [seq_length, 1] + block_j = block_indices.unsqueeze(0) # [1, seq_length] + block_diff = block_j - block_i # (n, n) + + return block_diff.expand(batch, self.num_attention_heads, seq_len, seq_len) + + def forward( + self, + hidden_states, + condition_vector, + speaker_embedding, + quantized_code, + time_step, + drop_audio_conditioning=False, + drop_code=False, + apply_cfg=True, + **kwargs, + ): + batch_size = hidden_states.shape[0] + if time_step.ndim == 0: + time_step = time_step.repeat(batch_size) + + # Compute embeddings + time_embedding = self.time_embed(time_step) + text_embedding = self.text_embed(quantized_code, drop_code=False if apply_cfg else drop_code) + text_embedding_unconditioned = self.text_embed(quantized_code, drop_code=True) if apply_cfg else None + + hidden_states = self.input_embed( + hidden_states, + speaker_embedding, + condition_vector, + text_embedding, + drop_audio_cond=drop_audio_conditioning, + code_embed_uncond=text_embedding_unconditioned, + apply_cfg=apply_cfg, + ) + + # Compute positional encodings + position_ids = torch.arange(hidden_states.shape[1], device=hidden_states.device) + position_ids = position_ids[None, :].repeat(batch_size, 1) + position_embeddings = self.rotary_embed(hidden_states, position_ids) + blockwise_difference = self._create_block_diff(hidden_states) + + # Transformer blocks + for transformer_block in self.transformer_blocks: + hidden_states = transformer_block( + hidden_states, + time_embedding, + position_embeddings=position_embeddings, + block_diff=blockwise_difference, + ) + + hidden_states = self.norm_out(hidden_states, time_embedding) + output = self.proj_out(hidden_states) + + return output + + @torch.no_grad() + def sample( + self, + conditioning_vector, + reference_mel_spectrogram, + quantized_code, + num_steps=10, + guidance_scale=0.5, + sway_coefficient=-1.0, + ): + maximum_duration = quantized_code.shape[1] * self.repeats + batch_size = reference_mel_spectrogram.shape[0] + if batch_size != 1: + raise ValueError("Only batch size = 1 is currently supported") + + if maximum_duration > self.config.max_position_embeddings: + raise ValueError( + f"Requested mel length ({maximum_duration}) exceeds `dit_config.max_position_embeddings` " + f"({self.config.max_position_embeddings}). Provide shorter `quantized_code`." + ) + + initial_state = torch.randn( + [batch_size, maximum_duration, self.mel_dim], + dtype=reference_mel_spectrogram.dtype, + device=quantized_code.device, + ) + conditioning_vector = conditioning_vector.unsqueeze(1).repeat(1, maximum_duration, 1) + + def ode_function(time_step, hidden_states): + if guidance_scale < 1e-5: + prediction = self( + hidden_states=hidden_states, + speaker_embedding=conditioning_vector, + condition_vector=reference_mel_spectrogram, + quantized_code=quantized_code, + time_step=time_step, + drop_audio_conditioning=False, + drop_code=False, + apply_cfg=False, + ) + return prediction + + model_output = self( + hidden_states=hidden_states, + quantized_code=quantized_code, + speaker_embedding=conditioning_vector, + condition_vector=reference_mel_spectrogram, + time_step=time_step, + apply_cfg=True, + ) + guided_prediction, null_prediction = torch.chunk(model_output, 2, dim=0) + return guided_prediction + (guided_prediction - null_prediction) * guidance_scale + + initial_time = 0 + time_embedding = torch.linspace( + initial_time, 1, num_steps, device=quantized_code.device, dtype=conditioning_vector.dtype + ) + + if sway_coefficient is not None: + time_embedding += sway_coefficient * (torch.cos(torch.pi / 2 * time_embedding) - 1 + time_embedding) + + ode_solver = RungeKutta4ODESolver(function=ode_function, initial_value=initial_state) + solution_trajectory = ode_solver.integrate(time_embedding) + + generated_waveform = solution_trajectory[-1] + generated_mel_spectrogram = generated_waveform.permute(0, 2, 1) + return generated_mel_spectrogram + + +@auto_docstring( + custom_intro=""" + The full Qwen2.5Omni Token2Wav model. Consists a DiT model take speech tokens as input and predict mel spectrogram and a BigVGAN vocoder take mel spectrogram as input and predict waveform. + """ +) +class Qwen2_5OmniToken2WavModel(Qwen2_5OmniPreTrainedModel): + config: Qwen2_5OmniToken2WavConfig + base_model_prefix = "model" + input_modalities = "audio" + _no_split_modules = ["Qwen2_5OmniToken2WavDiTModel", "Qwen2_5OmniToken2WavBigVGANModel"] + + def __init__(self, config: Qwen2_5OmniToken2WavConfig): + super().__init__(config) + attn_impl = config._attn_implementation + if is_flash_attention_requested(config): + logger.warning_once( + "Qwen2_5OmniToken2WavModel must inference with fp32, but Flash Attention only supports fp16 and bf16, " + "attention implementation of Qwen2_5OmniToken2WavModel will fallback to sdpa." + ) + attn_impl = "sdpa" + elif config._attn_implementation == "eager": + logger.warning_once( + "Qwen2_5OmniToken2WavModel does not support eager attention implementation, fall back to sdpa" + ) + attn_impl = "sdpa" + self.code2wav_dit_model = Qwen2_5OmniToken2WavDiTModel._from_config( + config.dit_config, attn_implementation=attn_impl + ) + self.code2wav_bigvgan_model = Qwen2_5OmniToken2WavBigVGANModel._from_config( + config.bigvgan_config, attn_implementation=attn_impl + ) + + self.post_init() + + def forward( + self, + code, + conditioning, + reference_mel, + num_steps=10, + guidance_scale=0.5, + sway_coefficient=-1.0, + **kwargs, + ): + """Generates a waveform from input code and conditioning parameters.""" + + mel_spectrogram = self.code2wav_dit_model.sample( + conditioning, + reference_mel, + code, + num_steps=num_steps, + guidance_scale=guidance_scale, + sway_coefficient=sway_coefficient, + ) + + waveform = self.code2wav_bigvgan_model(mel_spectrogram) + + return waveform + + +############################ +# Start Qwen2.5Omni # +############################ + + +@auto_docstring( + custom_intro=""" + The full Qwen2.5Omni model, a multimodal model composed of 3 sub-models: + - [`Qwen2_5OmniThinkerForConditionalGeneration`]: + a causal auto-regressive transformer takes text, audio, image, video as input and predict text tokens. + - [`Qwen2_5OmniTalkerForConditionalGeneration`]: + a causal auto-regressive transformer takes thinker hidden states and response as input and predict speech tokens. + - [`Qwen2_5OmniToken2WavModel`]: + a DiT model take speech tokens as input and predict mel spectrogram and a BigVGAN vocoder take mel spectrogram as input and predict waveform. + """ +) +class Qwen2_5OmniForConditionalGeneration(Qwen2_5OmniPreTrainedModel, GenerationMixin): + config: Qwen2_5OmniConfig + output_modalities = ("audio", "text") + _no_split_modules = [ + "Qwen2_5OmniTalkerForConditionalGeneration", + "Qwen2_5OmniToken2WavModel", + ] + + def __init__(self, config): + super().__init__(config) + + self.thinker = Qwen2_5OmniThinkerForConditionalGeneration(config.thinker_config) + + self.has_talker = config.enable_audio_output + self.speaker_map = {} + if config.enable_audio_output: + self.enable_talker() + self.post_init() + + def enable_talker(self): + self.talker = Qwen2_5OmniTalkerForConditionalGeneration(self.config.talker_config) + self.token2wav = Qwen2_5OmniToken2WavModel(self.config.token2wav_config) + self.token2wav.float() + self.has_talker = True + + def load_speakers(self, path): + check_torch_load_is_safe() + for key, value in torch.load(path, weights_only=True).items(): + self.speaker_map[key] = value + logger.info(f"Speaker {list(self.speaker_map.keys())} loaded") + + def disable_talker(self): + if hasattr(self, "talker"): + del self.talker + if hasattr(self, "token2wav"): + del self.token2wav + self.has_talker = False + + @classmethod + def from_pretrained( + cls, + pretrained_model_name_or_path, + *model_args, + config=None, + cache_dir=None, + ignore_mismatched_sizes=False, + force_download=False, + local_files_only=False, + token=None, + revision="main", + use_safetensors=None, + weights_only=True, + **kwargs, + ): + model = super().from_pretrained( + pretrained_model_name_or_path, + *model_args, + config=config, + cache_dir=cache_dir, + ignore_mismatched_sizes=ignore_mismatched_sizes, + force_download=force_download, + local_files_only=local_files_only, + token=token, + revision=revision, + use_safetensors=use_safetensors, + weights_only=weights_only, + **kwargs, + ) + spk_path = cached_file( + pretrained_model_name_or_path, + "spk_dict.pt", + subfolder=kwargs.pop("subfolder", None), + cache_dir=kwargs.pop("cache_dir", None), + force_download=kwargs.pop("force_download", False), + proxies=kwargs.pop("proxies", None), + local_files_only=kwargs.pop("local_files_only", False), + token=token, + revision=kwargs.pop("revision", None), + ) + if spk_path is None: + raise ValueError(f"""{pretrained_model_name_or_path}/{spk_path} not exists""") + model.load_speakers(spk_path) + + return model + + @torch.no_grad() + @deprecate_kwarg("return_audio", version="v5", new_name="generation_mode") + # TODO: raushan, defaults should be saved in generation config + def generate( + self, + input_ids: torch.Tensor | None = None, + speaker: str = "Chelsie", + use_audio_in_video: bool = False, + thinker_max_new_tokens: int = 1024, + talker_max_new_tokens: int = 4096, + talker_do_sample: bool = True, + talker_top_k: int = 40, + talker_top_p: float = 0.8, + talker_temperature: float = 0.9, + talker_eos_token_id: list[int] = [8292, 8294], + talker_repetition_penalty: float = 1.05, + **kwargs, + ): + r""" + Generate text response and audio from input. + + Args: + input_ids (`Optional[torch.Tensor]`, *optional*): + Input ids, should obtain from processor. + speaker (`str` , defaults to "Chelsie"): + Which speaker should be used in audio response. + use_audio_in_video (`bool`, defaults to False): + Whether or not use audio track in video, should same as the parameter in `process_audio_info`. + generation_mode (`Optional[str]`, *optional*): + Whether or not return response in audio format. When `generation_mode="audio"`, this parameter is same as `config.enable_audio_output`. + kwargs (*optional*): + - Without a prefix, they will be entered as `**kwargs` for the `generate` method of each sub-model. + - With a *thinker_*, *talker_*, *token2wav_* prefix, they will be input for the `generate` method of the + thinker, talker and token2wav respectively. It has the priority over the keywords without a prefix. + Returns: + When `return_audio=False`: + - **Text** (`torch.Tensor`): Generated text token sequence. + When `return_audio=True`: + - **Text** (`torch.Tensor`): Generated text token sequence. + - **Audio waveform** (`torch.Tensor`): Generated audio waveform. + """ + # check `False` on purpose because the parameter can be `str/bool`. This is needed for BC + generation_mode = kwargs.pop("generation_mode", None) + return_audio = generation_mode != "text" and generation_mode is not False + + if speaker not in self.speaker_map: + raise ValueError(f"{speaker} is not available, available speakers: {self.speaker_map.keys()}") + if return_audio and not self.has_talker: + raise ValueError( + "Cannot use talker when talker module not initialized. Use `enable_talker` method or set enable_talker in config to enable talker." + ) + if return_audio is None: + return_audio = self.has_talker + if input_ids.shape[0] != 1 and return_audio: + raise NotImplementedError("Qwen2.5-Omni currently does not support batched inference with audio output") + + shared_kwargs = {"use_audio_in_video": use_audio_in_video} + thinker_kwargs = { + "max_new_tokens": thinker_max_new_tokens, + } + talker_kwargs = { + "max_new_tokens": talker_max_new_tokens, + "do_sample": talker_do_sample, + "top_k": talker_top_k, + "top_p": talker_top_p, + "temperature": talker_temperature, + "eos_token_id": talker_eos_token_id, + "repetition_penalty": talker_repetition_penalty, + } + token2wav_kwargs = {} + + for key, value in kwargs.items(): + if key.startswith("thinker_"): + thinker_kwargs[key[len("thinker_") :]] = value + elif key.startswith("talker_"): + talker_kwargs[key[len("talker_") :]] = value + elif key.startswith("token2wav_"): + token2wav_kwargs[key[len("token2wav_") :]] = value + # Process special input values + elif key == "feature_attention_mask": + thinker_kwargs[key] = value + talker_kwargs["audio_feature_lengths"] = torch.sum(value, dim=1) + elif key == "input_features" or key == "attention_mask": + thinker_kwargs[key] = value + # Put other key to shared kwargs + else: + shared_kwargs[key] = value + + # Merge kwargs + for key, value in shared_kwargs.items(): + if key not in thinker_kwargs: + thinker_kwargs[key] = value + if key not in talker_kwargs: + talker_kwargs[key] = value + if key not in token2wav_kwargs: + token2wav_kwargs[key] = value + speaker_params = self.speaker_map[speaker] + + # 1. Generate from thinker module + generate_audio = return_audio and self.has_talker + if generate_audio: + thinker_kwargs["output_hidden_states"] = True + thinker_kwargs["return_dict_in_generate"] = True + + thinker_result = self.thinker.generate(input_ids=input_ids, **thinker_kwargs) + + if not generate_audio: + return thinker_result + + # 2. Generate speech tokens from talker module + embeds_to_talker = thinker_result.hidden_states[0][0].clone().to(input_ids.device) + if thinker_kwargs.get("input_features") is not None: + audio_ids_mask = input_ids == self.config.thinker_config.audio_token_index + audio_mask = audio_ids_mask.unsqueeze(-1).expand_as(embeds_to_talker) + audio_mask_tensor = torch.zeros( + [audio_ids_mask.sum(), embeds_to_talker.shape[-1]], + dtype=embeds_to_talker.dtype, + device=input_ids.device, + ) + embeds_to_talker.masked_scatter_(audio_mask, audio_mask_tensor) + if thinker_kwargs.get("pixel_values") is not None: + image_ids_mask = input_ids == self.config.thinker_config.image_token_index + image_mask = image_ids_mask.unsqueeze(-1).expand_as(embeds_to_talker) + image_mask_tensor = torch.zeros( + [image_ids_mask.sum(), embeds_to_talker.shape[-1]], + dtype=embeds_to_talker.dtype, + device=input_ids.device, + ) + embeds_to_talker.masked_scatter_(image_mask, image_mask_tensor) + if thinker_kwargs.get("pixel_values_videos") is not None: + video_ids_mask = input_ids == self.config.thinker_config.video_token_index + video_mask = video_ids_mask.unsqueeze(-1).expand_as(embeds_to_talker) + video_mask_tensor = torch.zeros( + [video_ids_mask.sum(), embeds_to_talker.shape[-1]], + dtype=embeds_to_talker.dtype, + device=input_ids.device, + ) + embeds_to_talker.masked_scatter_(video_mask, video_mask_tensor) + + processed_thinker_hidden = ( + (embeds_to_talker,) + thinker_result.hidden_states[0][1:], + ) + thinker_result.hidden_states[1:] + thinker_generate_ids = thinker_result.sequences[:, input_ids.size(1) :].to(input_ids.device) + thinker_token_embeds = [ + token_hidden_states[0].to(input_ids.device) for token_hidden_states in processed_thinker_hidden + ] + thinker_hidden_states = [ + token_hidden_states[-1].to(input_ids.device) for token_hidden_states in processed_thinker_hidden + ] + + talker_text_bos_token = speaker_params["bos_token"] + talker_input_text_ids = torch.cat( + [ + input_ids, + torch.tensor([[talker_text_bos_token]], dtype=torch.long, device=input_ids.device), + thinker_generate_ids[:, :1], + ], + dim=-1, + ) + + talker_input_ids = torch.cat( + [ + torch.full_like(input_ids, fill_value=self.talker.codec_mask_token), + torch.tensor([[self.talker.codec_pad_token]], dtype=torch.long, device=input_ids.device), + torch.tensor([[self.talker.codec_bos_token]], dtype=torch.long, device=input_ids.device), + ], + dim=1, + ) + + thinker_embed_tokens = self.thinker.get_input_embeddings() + thinker_reply_part = torch.cat(thinker_hidden_states[1:], dim=1) + torch.cat(thinker_token_embeds[1:], dim=1) + talker_inputs_embeds = thinker_hidden_states[0] + thinker_token_embeds[0] + talker_text_bos_token = torch.tensor([[talker_text_bos_token]], dtype=torch.long, device=input_ids.device) + talker_text_bos_embed = thinker_embed_tokens(talker_text_bos_token).to(input_ids.device) + talker_inputs_embeds = torch.cat( + [ + talker_inputs_embeds, + talker_text_bos_embed, + thinker_reply_part[:, :1, :], + ], + dim=1, + ) + + eos_token = torch.tensor([[self.talker.text_eos_token]], dtype=torch.long, device=input_ids.device) + eos_embedding = thinker_embed_tokens(eos_token).to(input_ids.device) + + pad_token = torch.tensor([[self.talker.text_pad_token]], dtype=torch.long, device=input_ids.device) + pad_embedding = thinker_embed_tokens(pad_token).to(input_ids.device) + + thinker_reply_part = torch.cat( + [ + thinker_reply_part[:, 1:, :], + eos_embedding, + pad_embedding, + ], + dim=1, + ) + + talker_attention_mask = None + if "attention_mask" in kwargs: + talker_attention_mask = torch.cat( + [kwargs["attention_mask"], kwargs["attention_mask"].new_ones((1, 2))], dim=1 + ).to(input_ids.device) + + talker_result = self.talker.generate( + input_ids=talker_input_ids, + input_text_ids=talker_input_text_ids, + thinker_reply_part=thinker_reply_part, + inputs_embeds=talker_inputs_embeds, + attention_mask=talker_attention_mask, + suppress_tokens=[self.talker.codec_bos_token], + **{k: (v.to(input_ids.device) if torch.is_tensor(v) else v) for k, v in talker_kwargs.items()}, + ) + talker_generate_codes = talker_result[:, talker_input_ids.shape[1] : -1] + + # 3. Generate wavs from code + if self.token2wav.dtype != torch.float: + self.token2wav.float() + + wav = self.token2wav( + talker_generate_codes.to(input_ids.device), + conditioning=speaker_params["cond"].to(input_ids.device).float(), + reference_mel=speaker_params["ref_mel"].to(input_ids.device).float(), + **token2wav_kwargs, + ) + + return thinker_result.sequences, wav.float() + + +__all__ = [ + "Qwen2_5OmniConfig", + "Qwen2_5OmniThinkerConfig", + "Qwen2_5OmniTalkerConfig", + "Qwen2_5OmniToken2WavConfig", + "Qwen2_5OmniForConditionalGeneration", + "Qwen2_5OmniThinkerTextModel", + "Qwen2_5OmniThinkerForConditionalGeneration", + "Qwen2_5OmniTalkerModel", + "Qwen2_5OmniTalkerForConditionalGeneration", + "Qwen2_5OmniToken2WavDiTModel", + "Qwen2_5OmniToken2WavBigVGANModel", + "Qwen2_5OmniToken2WavModel", + "Qwen2_5OmniPreTrainedModel", + "Qwen2_5OmniPreTrainedModelForConditionalGeneration", +] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/qwen2_5_omni/processing_qwen2_5_omni.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/qwen2_5_omni/processing_qwen2_5_omni.py new file mode 100644 index 0000000000000000000000000000000000000000..dcc98856ddc25fa41ca9d92bce1f84148bc3d632 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/qwen2_5_omni/processing_qwen2_5_omni.py @@ -0,0 +1,397 @@ +# Copyright 2025 The Qwen team, Alibaba Group and the HuggingFace Inc. team. All rights reserved. +# +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +""" +Processor class for Qwen2.5Omni. +""" + +import logging +import re + +import numpy as np + +from ...feature_extraction_utils import BatchFeature +from ...image_utils import ImageInput +from ...processing_utils import ProcessingKwargs, ProcessorMixin, Unpack, VideosKwargs +from ...tokenization_utils_base import AudioInput, PreTokenizedInput, TextInput +from ...utils import auto_docstring +from ...video_utils import VideoInput + + +# Redefine kwargs for videos because Qwen-Omni uses some kwargs for processing omni +# and does not use them in video processor class +class Qwen2_5_OmniVideosKwargs(VideosKwargs, total=False): + """ + min_pixels (`int`, *optional*): + Minimum number of pixels (height × width) for video frames after resizing. Frames smaller than this + threshold will be upscaled to meet the minimum requirement. + max_pixels (`int`, *optional*): + Maximum number of pixels (height × width) for video frames after resizing. Frames larger than this + threshold will be downscaled to fit within the limit. + patch_size (`int`, *optional*): + The spatial patch size used by the vision encoder. Video frames are divided into patches of this size + in both height and width dimensions. + temporal_patch_size (`int`, *optional*): + The temporal patch size used by the vision encoder. This determines how many consecutive frames are + grouped together as a single temporal patch. + merge_size (`int`, *optional*): + The merge size used for combining spatial patches. Multiple patches are merged together to reduce the + sequence length while maintaining spatial information. + min_frames (`int`, *optional*): + Minimum number of frames to extract from the video. Videos with fewer frames will be padded or repeated + to meet this requirement. + max_frames (`int`, *optional*): + Maximum number of frames to extract from the video. Longer videos will be truncated or sampled to fit + within this limit. + use_audio_in_video (`bool`, *optional*, defaults to `False`): + Whether to incorporate audio information when processing videos. When enabled, audio tokens are + interleaved with video tokens based on temporal alignment, creating a unified multimodal representation. + seconds_per_chunk (`float`, *optional*, defaults to `2.0`): + The duration (in seconds) of each video chunk when splitting long videos. This parameter controls how + videos are divided into temporal segments for processing. + position_id_per_seconds (`int` or `float`, *optional*, defaults to `25`): + The number of position IDs allocated per second of video. This parameter controls the temporal resolution + of position embeddings and is used to align video tokens with audio tokens when `use_audio_in_video=True`. + """ + + min_pixels: int + max_pixels: int + patch_size: int + temporal_patch_size: int + merge_size: int + min_frames: int + max_frames: int + use_audio_in_video: bool + seconds_per_chunk: float + position_id_per_seconds: int | float + + +class Qwen2_5OmniProcessorKwargs(ProcessingKwargs, total=False): + videos_kwargs: Qwen2_5_OmniVideosKwargs + + _defaults = { + "text_kwargs": { + "padding": False, + "padding_side": "left", + }, + "videos_kwargs": { + "seconds_per_chunk": 2.0, + "position_id_per_seconds": 25, + "use_audio_in_video": False, + "size": { + "shortest_edge": 128 * 28 * 28, + "longest_edge": 768 * 28 * 28, + }, + }, + "audio_kwargs": { + "sampling_rate": 16000, + "padding": "max_length", + "return_attention_mask": True, + }, + } + + +@auto_docstring +class Qwen2_5OmniProcessor(ProcessorMixin): + def __init__( + self, image_processor=None, video_processor=None, feature_extractor=None, tokenizer=None, chat_template=None + ): + super().__init__(image_processor, video_processor, feature_extractor, tokenizer, chat_template=chat_template) + self.image_token = self.tokenizer.image_token + self.audio_token = self.tokenizer.audio_token + self.video_token = self.tokenizer.video_token + self.vision_bos_token = self.tokenizer.vision_bos_token + self.vision_eos_token = self.tokenizer.vision_eos_token + self.audio_bos_token = self.tokenizer.audio_bos_token + self.audio_eos_token = self.tokenizer.audio_eos_token + + @auto_docstring + def __call__( + self, + text: TextInput | PreTokenizedInput | list[TextInput] | list[PreTokenizedInput] = None, + images: ImageInput | None = None, + videos: VideoInput | None = None, + audio: AudioInput | None = None, + **kwargs: Unpack[Qwen2_5OmniProcessorKwargs], + ) -> BatchFeature: + if text is None: + raise ValueError("You need to specify either a `text` input to process.") + + output_kwargs = self._merge_kwargs( + Qwen2_5OmniProcessorKwargs, + tokenizer_init_kwargs=self.tokenizer.init_kwargs, + **kwargs, + ) + + seconds_per_chunk = output_kwargs["videos_kwargs"].pop("seconds_per_chunk") + position_id_per_seconds = output_kwargs["videos_kwargs"].pop("position_id_per_seconds") + use_audio_in_video = output_kwargs["videos_kwargs"].pop("use_audio_in_video") + + if audio is not None: + output_kwargs["audio_kwargs"]["padding"] = "max_length" # Support "max_length" padding only here + audio_inputs = self.feature_extractor(audio, **output_kwargs["audio_kwargs"]) + audio_inputs["feature_attention_mask"] = audio_inputs.pop( + "attention_mask" + ) # rename feature_attention_mask to prevent conflicts later on + audio_inputs["input_features"] = audio_inputs.pop( + "input_features" + ) # rename input_features to prevent conflicts later on + input_lengths = (audio_inputs["feature_attention_mask"].sum(-1) - 1) // 2 + 1 + audio_lengths = iter((input_lengths - 2) // 2 + 1) + else: + audio_inputs = {} + audio_lengths = iter([]) + + if images is not None: + images_inputs = self.image_processor(images=images, **output_kwargs["images_kwargs"]) + image_grid_thw = iter(images_inputs["image_grid_thw"]) + else: + images_inputs = {} + image_grid_thw = iter([]) + + if videos is not None: + videos_inputs = self.video_processor(videos=videos, **output_kwargs["videos_kwargs"]) + + fps = output_kwargs["videos_kwargs"].get("fps", 2.0) + video_grid_thw = videos_inputs["video_grid_thw"] + second_per_grid_ts = [self.video_processor.temporal_patch_size / fps] * len(video_grid_thw) + videos_inputs["video_second_per_grid"] = second_per_grid_ts + + video_grid_thw = iter(video_grid_thw) + video_second_per_grid = iter(second_per_grid_ts) + else: + videos_inputs = {} + video_grid_thw = iter([]) + video_second_per_grid = iter([]) + + if not isinstance(text, list): + text = [text] + + if images is not None or videos is not None or audio is not None: + text = self.replace_multimodal_special_tokens( + text, + audio_lengths, + image_grid_thw, + video_grid_thw, + video_second_per_grid=video_second_per_grid, + use_audio_in_video=use_audio_in_video, + position_id_per_seconds=position_id_per_seconds, + seconds_per_chunk=seconds_per_chunk, + ) + + texts_inputs = self.tokenizer(text, **output_kwargs["text_kwargs"]) + + return BatchFeature( + data={**texts_inputs, **images_inputs, **videos_inputs, **audio_inputs}, + tensor_type=kwargs.get("return_tensors"), + ) + + def replace_multimodal_special_tokens( + self, + text, + audio_lengths, + image_grid_thw, + video_grid_thw, + video_second_per_grid, + use_audio_in_video, + position_id_per_seconds, + seconds_per_chunk, + ): + # Extend mm token length + merge_length_image = self.image_processor.merge_size**2 + merge_length_video = self.video_processor.merge_size**2 + + processed_text = [] + for sample in text: + positions = [] + special_tokens = [re.escape(tok) for tok in [self.audio_token, self.image_token, self.video_token]] + pattern = "|".join(special_tokens) + positions = sorted([(match.start(), match.group()) for match in re.finditer(pattern, sample)]) + positions.sort(key=lambda x: x[0]) + + for _, special_token in positions: + if special_token == self.audio_token: + sample = sample.replace(self.audio_token, "<|audio_placeholder|>" * next(audio_lengths), 1) + elif special_token == self.image_token: + image_seq_length = next(image_grid_thw).prod() // merge_length_image + sample = sample.replace(self.image_token, "<|image_placeholder|>" * image_seq_length, 1) + elif special_token == self.video_token: + if not use_audio_in_video: + video_seq_length = next(video_grid_thw).prod() // merge_length_video + sample = sample.replace(self.video_token, "<|video_placeholder|>" * video_seq_length, 1) + else: + audio_token_indices = np.arange(next(audio_lengths)) + curr_video_grid_thw = next(video_grid_thw) + height = curr_video_grid_thw[1] // self.video_processor.merge_size + width = curr_video_grid_thw[2] // self.video_processor.merge_size + video_token_indices = np.arange(curr_video_grid_thw[0]).reshape(-1, 1, 1) + video_token_indices = np.broadcast_to( + video_token_indices, (video_token_indices.shape[0], height, width) + ).reshape(-1) + video_token_indices = ( + video_token_indices * next(video_second_per_grid) * position_id_per_seconds + ) + + tokens_per_chunk = int(position_id_per_seconds * seconds_per_chunk) + video_chunk_indexes = self.get_chunked_index(video_token_indices, tokens_per_chunk) + audio_chunk_indexes = self.get_chunked_index(audio_token_indices, tokens_per_chunk) + + placeholder_string = self.vision_bos_token + self.audio_bos_token + for j in range(max(len(video_chunk_indexes), len(audio_chunk_indexes))): + if j < len(video_chunk_indexes): + video_seq_length = video_chunk_indexes[j][1] - video_chunk_indexes[j][0] + placeholder_string += "<|video_placeholder|>" * video_seq_length + if j < len(audio_chunk_indexes): + audio_seq_length = audio_chunk_indexes[j][1] - audio_chunk_indexes[j][0] + placeholder_string += "<|audio_placeholder|>" * audio_seq_length + placeholder_string += self.audio_eos_token + self.vision_eos_token + sample = sample.replace( + self.vision_bos_token + self.video_token + self.vision_eos_token, + placeholder_string, + 1, + ) + + sample = sample.replace("<|audio_placeholder|>", self.audio_token) + sample = sample.replace("<|image_placeholder|>", self.image_token) + sample = sample.replace("<|video_placeholder|>", self.video_token) + processed_text.append(sample) + return processed_text + + def get_chunked_index(self, token_indices: np.ndarray, tokens_per_chunk: int) -> list[tuple[int, int]]: + """ + Splits token index list into chunks based on token value ranges. + + Given a list of token indices, returns a list of (start, end) index tuples representing + slices of the list where the token values fall within successive ranges of `t_ntoken_per_chunk`. + + For example, if `t_ntoken_per_chunk` is 1000, the function will create chunks such that: + - the first chunk contains token values < 1000, + - the second chunk contains values >= 1000 and < 2000, and so on. + + Parameters: + token_indices (`np.ndarray`): A monotonically increasing list of token index values. + t_ntoken_per_chunk (`int`): Number of tokens per chunk (used as the chunk size threshold). + + Returns: + `list[tuple[int, int]]`: A list of tuples, each representing the start (inclusive) + and end (exclusive) indices of a chunk in `token_indices`. + """ + + def _iter(): + i, start_idx = 0, 0 # skip bos token + current_chunk = 1 + while i < len(token_indices): # skip eos token + if token_indices[i] >= current_chunk * tokens_per_chunk: + yield (start_idx, i) + start_idx = i + current_chunk += 1 + i += 1 + yield (start_idx, len(token_indices)) + + return list(_iter()) + + def apply_chat_template(self, conversations, chat_template=None, **kwargs): + is_batched = False + if isinstance(conversations[0], dict): + conversations = [conversations] + is_batched = True + + for conversation in conversations: + if ( + conversation[0]["role"] != "system" + or conversation[0]["content"][0]["text"] + != "You are Qwen, a virtual human developed by the Qwen Team, Alibaba Group, capable of perceiving auditory and visual inputs, as well as generating text and speech." + ): + logging.warning( + "System prompt modified, audio output may not work as expected. " + + "Audio output mode only works when using default system prompt 'You are Qwen, a virtual human developed by the Qwen Team, Alibaba Group, capable of perceiving auditory and visual inputs, as well as generating text and speech.'" + ) + if is_batched: + conversations = conversations[0] + + return super().apply_chat_template(conversations, chat_template, **kwargs) + + def post_process_image_text_to_text(self, generated_outputs, skip_special_tokens=True, **kwargs): + """ + Post-process the output of a vlm to decode the text. + + Args: + generated_outputs (`torch.Tensor` or `np.ndarray`): + The output of the model `generate` function. The output is expected to be a tensor of shape `(batch_size, sequence_length)` + or `(sequence_length,)`. + skip_special_tokens (`bool`, *optional*, defaults to `True`): + Whether or not to remove special tokens in the output. Argument passed to the tokenizer's `batch_decode` method. + **kwargs: + Additional arguments to be passed to the tokenizer's `batch_decode method`. + + Returns: + `list[str]`: The decoded text. + """ + return self.tokenizer.batch_decode(generated_outputs[0], skip_special_tokens=skip_special_tokens, **kwargs) + + def post_process_multimodal_output( + self, generated_outputs, skip_special_tokens=True, generation_mode=None, **kwargs + ): + """ + Post-process the output of a multimodal model to return the requested modality output. + If the model cannot generated the requested modality, an error will be raised. + + Args: + generated_outputs (`torch.Tensor` or `np.ndarray`): + The output of the model `generate` function. The output is expected to be a tensor of shape `(batch_size, sequence_length)` + or `(sequence_length,)`. + skip_special_tokens (`bool`, *optional*, defaults to `True`): + Whether or not to remove special tokens in the output. Argument passed to the tokenizer's `batch_decode` method. + generation_mode (`str`, *optional*): + Generation mode indicated which modality to output and can be one of `["text", "image", "audio"]`. + **kwargs: + Additional arguments to be passed to the tokenizer's `batch_decode method`. + + Returns: + `list[Inion[str, np.ndarray]]`: The decoded text or generated audio. + """ + if generation_mode is None or generation_mode == "text": + return self.post_process_image_text_to_text( + generated_outputs, skip_special_tokens=skip_special_tokens, **kwargs + ) + + elif generation_mode == "audio": + # model supports only bs=1, so we will never get several audio outputs + audio = generated_outputs[1].reshape(-1).detach().cpu().numpy() + return [audio] + + else: + raise ValueError( + f"{self.__class__.__name__} got an unexpected generation_mode={generation_mode}. Supported options are only `text` and `audio" + ) + + @property + def model_input_names(self): + tokenizer_input_names = self.tokenizer.model_input_names + feature_extractor_input_names = self.feature_extractor.model_input_names + image_processor_input_names = self.image_processor.model_input_names + video_processor_input_names = self.video_processor.model_input_names + return list( + dict.fromkeys( + tokenizer_input_names + + feature_extractor_input_names + + image_processor_input_names + + video_processor_input_names + + ["feature_attention_mask"] + + ["video_second_per_grid"] + ) + ) + + +__all__ = ["Qwen2_5OmniProcessor"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/qwen2_5_vl/__init__.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/qwen2_5_vl/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..7a9f44a7a05fc65136552948be9acef53e5ea106 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/qwen2_5_vl/__init__.py @@ -0,0 +1,28 @@ +# Copyright 2025 The Qwen Team and The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from typing import TYPE_CHECKING + +from ...utils import _LazyModule +from ...utils.import_utils import define_import_structure + + +if TYPE_CHECKING: + from .configuration_qwen2_5_vl import * + from .modeling_qwen2_5_vl import * + from .processing_qwen2_5_vl import * +else: + import sys + + _file = globals()["__file__"] + sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__) diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/qwen2_5_vl/configuration_qwen2_5_vl.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/qwen2_5_vl/configuration_qwen2_5_vl.py new file mode 100644 index 0000000000000000000000000000000000000000..c9bfcb9aadbe320a21a79e8cfc1aae3202d3b648 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/qwen2_5_vl/configuration_qwen2_5_vl.py @@ -0,0 +1,322 @@ +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# This file was automatically generated from src/transformers/models/qwen2_5_vl/modular_qwen2_5_vl.py. +# Do NOT edit this file manually as any edits will be overwritten by the generation of +# the file from the modular. If any change should be done, please apply the change to the +# modular_qwen2_5_vl.py file directly. One of our CI enforces this. +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# Copyright 2025 The Qwen Team and The HuggingFace Inc. team. All rights reserved. +# +# This code is based on EleutherAI's GPT-NeoX library and the GPT-NeoX +# and OPT implementations in this library. It has been modified from its +# original forms to accommodate minor architectural differences compared +# to GPT-NeoX and OPT used by the Meta AI team that trained the model. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +import inspect + +from ...configuration_utils import PreTrainedConfig, layer_type_validation +from ...modeling_rope_utils import RopeParameters + + +class Qwen2_5_VLVisionConfig(PreTrainedConfig): + model_type = "qwen2_5_vl" + base_config_key = "vision_config" + + def __init__( + self, + depth=32, + hidden_size=3584, + hidden_act="silu", + intermediate_size=3420, + num_heads=16, + in_channels=3, + patch_size=14, + spatial_merge_size=2, + temporal_patch_size=2, + tokens_per_second=4, + window_size=112, + out_hidden_size=3584, + fullatt_block_indexes=[7, 15, 23, 31], + initializer_range=0.02, + **kwargs, + ): + super().__init__(**kwargs) + + self.depth = depth + self.hidden_size = hidden_size + self.hidden_act = hidden_act + self.intermediate_size = intermediate_size + self.num_heads = num_heads + self.in_channels = in_channels + self.patch_size = patch_size + self.spatial_merge_size = spatial_merge_size + self.temporal_patch_size = temporal_patch_size + self.tokens_per_second = tokens_per_second + self.window_size = window_size + self.fullatt_block_indexes = fullatt_block_indexes + self.out_hidden_size = out_hidden_size + self.initializer_range = initializer_range + + +class Qwen2_5_VLTextConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`Qwen2_5_VLTextModel`]. It is used to instantiate a + Qwen2-VL model according to the specified arguments, defining the model architecture. Instantiating a configuration + with the defaults will yield a similar configuration to that of + Qwen2-VL-7B-Instruct [Qwen/Qwen2-VL-7B-Instruct](https://huggingface.co/Qwen/Qwen2-VL-7B-Instruct). + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + vocab_size (`int`, *optional*, defaults to 152064): + Vocabulary size of the Qwen2_5_VL model. Defines the number of different tokens that can be represented by the + `inputs_ids` passed when calling [`Qwen2_5_VLModel`] + hidden_size (`int`, *optional*, defaults to 8192): + Dimension of the hidden representations. + intermediate_size (`int`, *optional*, defaults to 29568): + Dimension of the MLP representations. + num_hidden_layers (`int`, *optional*, defaults to 80): + Number of hidden layers in the Transformer encoder. + num_attention_heads (`int`, *optional*, defaults to 64): + Number of attention heads for each attention layer in the Transformer encoder. + num_key_value_heads (`int`, *optional*, defaults to 8): + This is the number of key_value heads that should be used to implement Grouped Query Attention. If + `num_key_value_heads=num_attention_heads`, the model will use Multi Head Attention (MHA), if + `num_key_value_heads=1` the model will use Multi Query Attention (MQA) otherwise GQA is used. When + converting a multi-head checkpoint to a GQA checkpoint, each group key and value head should be constructed + by meanpooling all the original heads within that group. For more details, check out [this + paper](https://huggingface.co/papers/2305.13245). If it is not specified, will default to `32`. + hidden_act (`str` or `function`, *optional*, defaults to `"silu"`): + The non-linear activation function (function or string) in the decoder. + max_position_embeddings (`int`, *optional*, defaults to 32768): + The maximum sequence length that this model might ever be used with. + initializer_range (`float`, *optional*, defaults to 0.02): + The standard deviation of the truncated_normal_initializer for initializing all weight matrices. + rms_norm_eps (`float`, *optional*, defaults to 1e-05): + The epsilon used by the rms normalization layers. + use_cache (`bool`, *optional*, defaults to `True`): + Whether or not the model should return the last key/values attentions (not used by all models). Only + relevant if `config.is_decoder=True`. + use_sliding_window (`bool`, *optional*, defaults to `False`): + Whether to use sliding window attention. + sliding_window (`int`, *optional*, defaults to 4096): + Sliding window attention (SWA) window size. If not specified, will default to `4096`. + max_window_layers (`int`, *optional*, defaults to 80): + The number of layers using full attention. The first `max_window_layers` layers will use full attention, while any + additional layer afterwards will use SWA (Sliding Window Attention). + layer_types (`list`, *optional*): + Attention pattern for each layer. + attention_dropout (`float`, *optional*, defaults to 0.0): + The dropout ratio for the attention probabilities. + rope_parameters (`RopeParameters`, *optional*): + Dictionary containing the configuration parameters for the RoPE embeddings. The dictionary should contain + a value for `rope_theta` and optionally parameters used for scaling in case you want to use RoPE + with longer `max_position_embeddings`. + bos_token_id (`int`, *optional*, defaults to 151643): + The id of the _beginning-of-stream_ token. + eos_token_id (`int`, *optional*, defaults to 151645): + The id of the _end-of-stream_ token. + pad_token_id (`int`, *optional*): + The id of the _padding_ token. + + ```python + >>> from transformers import Qwen2_5_VLTextModel, Qwen2_5_VLConfig + + >>> # Initializing a Qwen2_5_VL style configuration + >>> configuration = Qwen2_5_VLConfig() + + >>> # Initializing a model from the Qwen2-VL-7B style configuration + >>> model = Qwen2_5_VLTextModel(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "qwen2_5_vl_text" + base_config_key = "text_config" + keys_to_ignore_at_inference = ["past_key_values"] + default_theta = 1000000.0 + # Default tensor parallel plan for base model `Qwen2_5_VL` + base_model_tp_plan = { + "layers.*.self_attn.q_proj": "colwise", + "layers.*.self_attn.k_proj": "colwise", + "layers.*.self_attn.v_proj": "colwise", + "layers.*.self_attn.o_proj": "rowwise", + "layers.*.mlp.gate_proj": "colwise", + "layers.*.mlp.up_proj": "colwise", + "layers.*.mlp.down_proj": "rowwise", + } + base_model_pp_plan = { + "embed_tokens": (["input_ids"], ["inputs_embeds"]), + "layers": (["hidden_states", "attention_mask"], ["hidden_states"]), + "norm": (["hidden_states"], ["hidden_states"]), + } + + def __init__( + self, + vocab_size: int | None = 152064, + hidden_size: int | None = 8192, + intermediate_size: int | None = 29568, + num_hidden_layers: int | None = 80, + num_attention_heads: int | None = 64, + num_key_value_heads: int | None = 8, + hidden_act: str | None = "silu", + max_position_embeddings: int | None = 32768, + initializer_range: float | None = 0.02, + rms_norm_eps: int | None = 1e-05, + use_cache: bool | None = True, + use_sliding_window: bool | None = False, + sliding_window: int | None = 4096, + max_window_layers: int | None = 80, + layer_types: list[str] | None = None, + attention_dropout: float | None = 0.0, + rope_parameters: RopeParameters | dict[str, RopeParameters] | None = None, + bos_token_id: int | None = 151643, + eos_token_id: int | None = 151645, + pad_token_id: int | None = None, + **kwargs, + ): + self.vocab_size = vocab_size + self.max_position_embeddings = max_position_embeddings + self.hidden_size = hidden_size + self.intermediate_size = intermediate_size + self.num_hidden_layers = num_hidden_layers + self.num_attention_heads = num_attention_heads + self.use_sliding_window = use_sliding_window + self.sliding_window = sliding_window if self.use_sliding_window else None + self.max_window_layers = max_window_layers + + # for backward compatibility + if num_key_value_heads is None: + num_key_value_heads = num_attention_heads + + self.num_key_value_heads = num_key_value_heads + self.hidden_act = hidden_act + self.initializer_range = initializer_range + self.rms_norm_eps = rms_norm_eps + self.use_cache = use_cache + self.attention_dropout = attention_dropout + + self.layer_types = layer_types + if self.layer_types is None: + self.layer_types = [ + "sliding_attention" + if self.sliding_window is not None and i >= self.max_window_layers + else "full_attention" + for i in range(self.num_hidden_layers) + ] + layer_type_validation(self.layer_types, self.num_hidden_layers) + + self.rope_parameters = rope_parameters + self.bos_token_id = bos_token_id + self.eos_token_id = eos_token_id + self.pad_token_id = pad_token_id + super().__init__( + ignore_keys_at_rope_validation={"mrope_section"}, + **kwargs, + ) + + def convert_rope_params_to_dict(self, ignore_keys_at_rope_validation: set | None = None, **kwargs): + rope_scaling = kwargs.pop("rope_scaling", None) + self.rope_parameters = rope_scaling or self.rope_parameters + self.rope_parameters = self.rope_parameters if self.rope_parameters is not None else {} + + # Standardize and validate the correctness of rotary position embeddings parameters + self.rope_parameters.setdefault("rope_theta", kwargs.pop("rope_theta", self.default_theta)) + if self.rope_parameters.get("rope_type", self.rope_parameters.get("type")) == "mrope": + self.rope_parameters["rope_type"] = "default" + self.standardize_rope_params() + self.validate_rope(ignore_keys=ignore_keys_at_rope_validation) + return kwargs + + +class Qwen2_5_VLConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`Qwen2_5_VLModel`]. It is used to instantiate a + Qwen2-VL model according to the specified arguments, defining the model architecture. Instantiating a configuration + with the defaults will yield a similar configuration to that of + Qwen2-VL-7B-Instruct [Qwen/Qwen2-VL-7B-Instruct](https://huggingface.co/Qwen/Qwen2-VL-7B-Instruct). + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + + Args: + text_config (`Union[PreTrainedConfig, dict]`, *optional*, defaults to `Qwen2_5_VLTextConfig`): + The config object or dictionary of the text backbone. + vision_config (`Union[PreTrainedConfig, dict]`, *optional*, defaults to `Qwen2_5_VLVisionConfig`): + The config object or dictionary of the vision backbone. + image_token_id (`int`, *optional*, defaults to 151655): + The image token index to encode the image prompt. + video_token_id (`int`, *optional*, defaults to 151656): + The video token index to encode the image prompt. + vision_start_token_id (`int`, *optional*, defaults to 151652): + The token index to denote start of vision input. + vision_end_token_id (`int`, *optional*, defaults to 151653): + The token index to denote end of vision input. + tie_word_embeddings (`bool`, *optional*, defaults to `False`): + Whether the model's input and output word embeddings should be tied. + + ```python + >>> from transformers import Qwen2_5_VLForConditionalGeneration, Qwen2_5_VLConfig + + >>> # Initializing a Qwen2_5_VL style configuration + >>> configuration = Qwen2_5_VLConfig() + + >>> # Initializing a model from the Qwen2-VL-7B style configuration + >>> model = Qwen2_5_VLForConditionalGeneration(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "qwen2_5_vl" + sub_configs = {"vision_config": Qwen2_5_VLVisionConfig, "text_config": Qwen2_5_VLTextConfig} + keys_to_ignore_at_inference = ["past_key_values"] + + def __init__( + self, + text_config=None, + vision_config=None, + image_token_id=151655, + video_token_id=151656, + vision_start_token_id=151652, + vision_end_token_id=151653, + tie_word_embeddings=False, + **kwargs, + ): + if isinstance(vision_config, dict): + self.vision_config = self.sub_configs["vision_config"](**vision_config) + elif vision_config is None: + self.vision_config = self.sub_configs["vision_config"]() + + if isinstance(text_config, dict): + self.text_config = self.sub_configs["text_config"](**text_config) + elif text_config is None: + # Hub configs are saved as flat dicts so we pop some of kwargs to init `TextConfig` + text_params = inspect.signature(self.sub_configs["text_config"].__init__).parameters.keys() + text_params = list(text_params) + ["rope_scaling", "rope_theta"] + text_config = {key: kwargs.pop(key) for key in text_params if key in kwargs} + text_config["dtype"] = kwargs.get("torch_dtype", kwargs.get("dtype")) # don't pop the dtype + self.text_config = self.sub_configs["text_config"](**text_config) + + self.image_token_id = image_token_id + self.video_token_id = video_token_id + self.vision_start_token_id = vision_start_token_id + self.vision_end_token_id = vision_end_token_id + self.tie_word_embeddings = tie_word_embeddings + super().__init__(**kwargs) + + +__all__ = ["Qwen2_5_VLConfig", "Qwen2_5_VLTextConfig"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/qwen2_5_vl/modeling_qwen2_5_vl.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/qwen2_5_vl/modeling_qwen2_5_vl.py new file mode 100644 index 0000000000000000000000000000000000000000..6305902014ce5cda0f09928415e0496f91c4c956 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/qwen2_5_vl/modeling_qwen2_5_vl.py @@ -0,0 +1,1837 @@ +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# This file was automatically generated from src/transformers/models/qwen2_5_vl/modular_qwen2_5_vl.py. +# Do NOT edit this file manually as any edits will be overwritten by the generation of +# the file from the modular. If any change should be done, please apply the change to the +# modular_qwen2_5_vl.py file directly. One of our CI enforces this. +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# Copyright 2025 The Qwen Team and The HuggingFace Inc. team. All rights reserved. +# +# This code is based on EleutherAI's GPT-NeoX library and the GPT-NeoX +# and OPT implementations in this library. It has been modified from its +# original forms to accommodate minor architectural differences compared +# to GPT-NeoX and OPT used by the Meta AI team that trained the model. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import itertools +from collections.abc import Callable +from dataclasses import dataclass +from typing import Any, Optional + +import torch +import torch.nn as nn +import torch.nn.functional as F + +from ... import initialization as init +from ...activations import ACT2FN +from ...cache_utils import Cache, DynamicCache +from ...generation import GenerationMixin +from ...integrations import use_kernel_forward_from_hub +from ...masking_utils import create_causal_mask, create_sliding_window_causal_mask +from ...modeling_flash_attention_utils import FlashAttentionKwargs +from ...modeling_layers import GradientCheckpointingLayer +from ...modeling_outputs import BaseModelOutputWithPast, BaseModelOutputWithPooling, ModelOutput +from ...modeling_rope_utils import ROPE_INIT_FUNCTIONS +from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel +from ...processing_utils import Unpack +from ...utils import TransformersKwargs, auto_docstring, can_return_tuple, logging, torch_compilable_check +from ...utils.generic import is_flash_attention_requested, maybe_autocast, merge_with_config_defaults +from ...utils.output_capturing import capture_outputs +from .configuration_qwen2_5_vl import Qwen2_5_VLConfig, Qwen2_5_VLTextConfig, Qwen2_5_VLVisionConfig + + +logger = logging.get_logger(__name__) + + +@use_kernel_forward_from_hub("RMSNorm") +class Qwen2_5_VLRMSNorm(nn.Module): + def __init__(self, hidden_size, eps: float = 1e-6) -> None: + """ + Qwen2_5_VLRMSNorm is equivalent to T5LayerNorm + """ + super().__init__() + self.weight = nn.Parameter(torch.ones(hidden_size)) + self.variance_epsilon = eps + + def forward(self, hidden_states: torch.Tensor) -> torch.Tensor: + input_dtype = hidden_states.dtype + hidden_states = hidden_states.to(torch.float32) + variance = hidden_states.pow(2).mean(-1, keepdim=True) + hidden_states = hidden_states * torch.rsqrt(variance + self.variance_epsilon) + return self.weight * hidden_states.to(input_dtype) + + def extra_repr(self): + return f"{tuple(self.weight.shape)}, eps={self.variance_epsilon}" + + +class Qwen2_5_VLMLP(nn.Module): + def __init__(self, config, bias: bool = False): + super().__init__() + self.hidden_size = config.hidden_size + self.intermediate_size = config.intermediate_size + self.gate_proj = nn.Linear(self.hidden_size, self.intermediate_size, bias=bias) + self.up_proj = nn.Linear(self.hidden_size, self.intermediate_size, bias=bias) + self.down_proj = nn.Linear(self.intermediate_size, self.hidden_size, bias=bias) + self.act_fn = ACT2FN[config.hidden_act] + + def forward(self, hidden_state): + return self.down_proj(self.act_fn(self.gate_proj(hidden_state)) * self.up_proj(hidden_state)) + + +class Qwen2_5_VisionPatchEmbed(nn.Module): + def __init__( + self, + patch_size: int = 14, + temporal_patch_size: int = 2, + in_channels: int = 3, + embed_dim: int = 1152, + ) -> None: + super().__init__() + self.patch_size = patch_size + self.temporal_patch_size = temporal_patch_size + self.in_channels = in_channels + self.embed_dim = embed_dim + + kernel_size = [temporal_patch_size, patch_size, patch_size] + self.proj = nn.Conv3d(in_channels, embed_dim, kernel_size=kernel_size, stride=kernel_size, bias=False) + + def forward(self, hidden_states: torch.Tensor) -> torch.Tensor: + target_dtype = self.proj.weight.dtype + hidden_states = hidden_states.view( + -1, self.in_channels, self.temporal_patch_size, self.patch_size, self.patch_size + ) + hidden_states = self.proj(hidden_states.to(dtype=target_dtype)).view(-1, self.embed_dim) + return hidden_states + + +class Qwen2_5_VisionRotaryEmbedding(nn.Module): + inv_freq: torch.Tensor # fix linting for `register_buffer` + + def __init__(self, dim: int, theta: float = 10000.0) -> None: + super().__init__() + self.dim = dim + self.theta = theta + inv_freq = 1.0 / (theta ** (torch.arange(0, dim, 2, dtype=torch.float) / dim)) + self.register_buffer("inv_freq", inv_freq, persistent=False) + + def forward(self, seqlen: int) -> torch.Tensor: + seq = torch.arange(seqlen, device=self.inv_freq.device, dtype=self.inv_freq.dtype) + freqs = torch.outer(seq, self.inv_freq) + return freqs + + +class Qwen2_5_VLPatchMerger(nn.Module): + def __init__(self, dim: int, context_dim: int, spatial_merge_size: int = 2) -> None: + super().__init__() + self.hidden_size = context_dim * (spatial_merge_size**2) + self.ln_q = Qwen2_5_VLRMSNorm(context_dim, eps=1e-6) + self.mlp = nn.Sequential( + nn.Linear(self.hidden_size, self.hidden_size), + nn.GELU(), + nn.Linear(self.hidden_size, dim), + ) + + def forward(self, x: torch.Tensor) -> torch.Tensor: + x = self.mlp(self.ln_q(x).view(-1, self.hidden_size)) + return x + + +def rotate_half(x): + """Rotates half the hidden dims of the input.""" + x1 = x[..., : x.shape[-1] // 2] + x2 = x[..., x.shape[-1] // 2 :] + return torch.cat((-x2, x1), dim=-1) + + +def apply_rotary_pos_emb_vision( + q: torch.Tensor, k: torch.Tensor, cos: torch.Tensor, sin: torch.Tensor +) -> tuple[torch.Tensor, torch.Tensor]: + orig_q_dtype = q.dtype + orig_k_dtype = k.dtype + q, k = q.float(), k.float() + cos, sin = cos.unsqueeze(-2).float(), sin.unsqueeze(-2).float() + q_embed = (q * cos) + (rotate_half(q) * sin) + k_embed = (k * cos) + (rotate_half(k) * sin) + q_embed = q_embed.to(orig_q_dtype) + k_embed = k_embed.to(orig_k_dtype) + return q_embed, k_embed + + +def repeat_kv(hidden_states: torch.Tensor, n_rep: int) -> torch.Tensor: + """ + This is the equivalent of torch.repeat_interleave(x, dim=1, repeats=n_rep). The hidden states go from (batch, + num_key_value_heads, seqlen, head_dim) to (batch, num_attention_heads, seqlen, head_dim) + """ + batch, num_key_value_heads, slen, head_dim = hidden_states.shape + if n_rep == 1: + return hidden_states + hidden_states = hidden_states[:, :, None, :, :].expand(batch, num_key_value_heads, n_rep, slen, head_dim) + return hidden_states.reshape(batch, num_key_value_heads * n_rep, slen, head_dim) + + +def eager_attention_forward( + module: nn.Module, + query: torch.Tensor, + key: torch.Tensor, + value: torch.Tensor, + attention_mask: torch.Tensor | None, + scaling: float, + dropout: float = 0.0, + **kwargs, +): + key_states = repeat_kv(key, module.num_key_value_groups) + value_states = repeat_kv(value, module.num_key_value_groups) + + attn_weights = torch.matmul(query, key_states.transpose(2, 3)) * scaling + if attention_mask is not None: + attn_weights = attn_weights + attention_mask + + attn_weights = nn.functional.softmax(attn_weights, dim=-1, dtype=torch.float32).to(query.dtype) + attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training) + attn_output = torch.matmul(attn_weights, value_states) + attn_output = attn_output.transpose(1, 2).contiguous() + + return attn_output, attn_weights + + +class Qwen2_5_VLVisionAttention(nn.Module): + def __init__(self, config: Qwen2_5_VLVisionConfig) -> None: + super().__init__() + self.dim = config.hidden_size + self.num_heads = config.num_heads + self.head_dim = self.dim // self.num_heads + self.num_key_value_groups = 1 # needed for eager attention + self.qkv = nn.Linear(self.dim, self.dim * 3, bias=True) + self.proj = nn.Linear(self.dim, self.dim) + self.scaling = self.head_dim**-0.5 + self.config = config + self.attention_dropout = 0.0 + self.is_causal = False + + def forward( + self, + hidden_states: torch.Tensor, + cu_seqlens: torch.Tensor, + rotary_pos_emb: torch.Tensor | None = None, + position_embeddings: tuple[torch.Tensor, torch.Tensor] | None = None, + **kwargs, + ) -> torch.Tensor: + seq_length = hidden_states.shape[0] + query_states, key_states, value_states = ( + self.qkv(hidden_states).reshape(seq_length, 3, self.num_heads, -1).permute(1, 0, 2, 3).unbind(0) + ) + cos, sin = position_embeddings + query_states, key_states = apply_rotary_pos_emb_vision(query_states, key_states, cos, sin) + + query_states = query_states.transpose(0, 1).unsqueeze(0) + key_states = key_states.transpose(0, 1).unsqueeze(0) + value_states = value_states.transpose(0, 1).unsqueeze(0) + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, eager_attention_forward + ) + + if is_flash_attention_requested(self.config): + # Flash Attention: Use cu_seqlens for variable length attention + max_seqlen = (cu_seqlens[1:] - cu_seqlens[:-1]).max() + attn_output, _ = attention_interface( + self, + query_states, + key_states, + value_states, + attention_mask=None, + scaling=self.scaling, + dropout=0.0 if not self.training else self.attention_dropout, + cu_seq_lens_q=cu_seqlens, + cu_seq_lens_k=cu_seqlens, + max_length_q=max_seqlen, + max_length_k=max_seqlen, + is_causal=False, + **kwargs, + ) + else: + # Other implementations: Process each chunk separately + lengths = cu_seqlens[1:] - cu_seqlens[:-1] + splits = [ + torch.split(tensor, lengths.tolist(), dim=2) for tensor in (query_states, key_states, value_states) + ] + + attn_outputs = [ + attention_interface( + self, + q, + k, + v, + attention_mask=None, + scaling=self.scaling, + dropout=0.0 if not self.training else self.attention_dropout, + is_causal=False, + **kwargs, + )[0] + for q, k, v in zip(*splits) + ] + attn_output = torch.cat(attn_outputs, dim=1) + + attn_output = attn_output.reshape(seq_length, -1).contiguous() + attn_output = self.proj(attn_output) + return attn_output + + +class Qwen2_5_VLVisionBlock(GradientCheckpointingLayer): + def __init__(self, config, attn_implementation: str = "sdpa") -> None: + super().__init__() + self.norm1 = Qwen2_5_VLRMSNorm(config.hidden_size, eps=1e-6) + self.norm2 = Qwen2_5_VLRMSNorm(config.hidden_size, eps=1e-6) + self.attn = Qwen2_5_VLVisionAttention(config=config) + self.mlp = Qwen2_5_VLMLP(config, bias=True) + + def forward( + self, + hidden_states: torch.Tensor, + cu_seqlens: torch.Tensor, + rotary_pos_emb: torch.Tensor | None = None, + position_embeddings: tuple[torch.Tensor, torch.Tensor] | None = None, + **kwargs, + ) -> torch.Tensor: + hidden_states = hidden_states + self.attn( + self.norm1(hidden_states), + cu_seqlens=cu_seqlens, + rotary_pos_emb=rotary_pos_emb, + position_embeddings=position_embeddings, + **kwargs, + ) + hidden_states = hidden_states + self.mlp(self.norm2(hidden_states)) + return hidden_states + + +@auto_docstring +class Qwen2_5_VLPreTrainedModel(PreTrainedModel): + config: Qwen2_5_VLConfig + base_model_prefix = "model" + input_modalities = ("image", "video", "text") + supports_gradient_checkpointing = True + _no_split_modules = ["Qwen2_5_VLDecoderLayer", "Qwen2_5_VLVisionBlock"] + _skip_keys_device_placement = "past_key_values" + _supports_flash_attn = True + _supports_sdpa = True + + _can_compile_fullgraph = True + _supports_attention_backend = True + + def _init_weights(self, module): + super()._init_weights(module) + if isinstance(module, Qwen2_5_VisionRotaryEmbedding): + inv_freq = 1.0 / (module.theta ** (torch.arange(0, module.dim, 2, dtype=torch.float) / module.dim)) + init.copy_(module.inv_freq, inv_freq) + + +class Qwen2_5_VisionTransformerPretrainedModel(Qwen2_5_VLPreTrainedModel): + config: Qwen2_5_VLVisionConfig + _no_split_modules = ["Qwen2_5_VLVisionBlock"] + _input_embed_layer = "patch_embed" + _can_record_outputs = { + "hidden_states": Qwen2_5_VLVisionBlock, + "attentions": Qwen2_5_VLVisionAttention, + } + + def __init__(self, config, *inputs, **kwargs) -> None: + super().__init__(config, *inputs, **kwargs) + self.spatial_merge_size = config.spatial_merge_size + self.patch_size = config.patch_size + self.fullatt_block_indexes = config.fullatt_block_indexes + self.window_size = config.window_size + self.spatial_merge_unit = self.spatial_merge_size * self.spatial_merge_size + + self.patch_embed = Qwen2_5_VisionPatchEmbed( + patch_size=config.patch_size, + temporal_patch_size=config.temporal_patch_size, + in_channels=config.in_channels, + embed_dim=config.hidden_size, + ) + + head_dim = config.hidden_size // config.num_heads + self.rotary_pos_emb = Qwen2_5_VisionRotaryEmbedding(head_dim // 2) + + self.blocks = nn.ModuleList([Qwen2_5_VLVisionBlock(config) for _ in range(config.depth)]) + self.merger = Qwen2_5_VLPatchMerger( + dim=config.out_hidden_size, + context_dim=config.hidden_size, + spatial_merge_size=config.spatial_merge_size, + ) + self.gradient_checkpointing = False + + self.post_init() + + def rot_pos_emb(self, grid_thw): + pos_ids = [] + for t, h, w in grid_thw.tolist(): + hpos_ids = torch.arange(h).unsqueeze(1).expand(-1, w) + hpos_ids = hpos_ids.reshape( + h // self.spatial_merge_size, + self.spatial_merge_size, + w // self.spatial_merge_size, + self.spatial_merge_size, + ) + hpos_ids = hpos_ids.permute(0, 2, 1, 3) + hpos_ids = hpos_ids.flatten() + + wpos_ids = torch.arange(w).unsqueeze(0).expand(h, -1) + wpos_ids = wpos_ids.reshape( + h // self.spatial_merge_size, + self.spatial_merge_size, + w // self.spatial_merge_size, + self.spatial_merge_size, + ) + wpos_ids = wpos_ids.permute(0, 2, 1, 3) + wpos_ids = wpos_ids.flatten() + pos_ids.append(torch.stack([hpos_ids, wpos_ids], dim=-1).repeat(t, 1)) + pos_ids = torch.cat(pos_ids, dim=0) + max_grid_size = grid_thw[:, 1:].max() + rotary_pos_emb_full = self.rotary_pos_emb(max_grid_size) + rotary_pos_emb = rotary_pos_emb_full[pos_ids].flatten(1) + return rotary_pos_emb + + def get_window_index(self, grid_thw): + window_index: list = [] + cu_window_seqlens: list = [0] + window_index_id = 0 + vit_merger_window_size = self.window_size // self.spatial_merge_size // self.patch_size + grid_thw_list = grid_thw.tolist() + + for grid_t, grid_h, grid_w in grid_thw_list: + llm_grid_h, llm_grid_w = ( + grid_h // self.spatial_merge_size, + grid_w // self.spatial_merge_size, + ) + index = torch.arange(grid_t * llm_grid_h * llm_grid_w).reshape(grid_t, llm_grid_h, llm_grid_w) + pad_h = vit_merger_window_size - llm_grid_h % vit_merger_window_size + pad_w = vit_merger_window_size - llm_grid_w % vit_merger_window_size + num_windows_h = (llm_grid_h + pad_h) // vit_merger_window_size + num_windows_w = (llm_grid_w + pad_w) // vit_merger_window_size + index_padded = F.pad(index, (0, pad_w, 0, pad_h), "constant", -100) + index_padded = index_padded.reshape( + grid_t, + num_windows_h, + vit_merger_window_size, + num_windows_w, + vit_merger_window_size, + ) + index_padded = index_padded.permute(0, 1, 3, 2, 4).reshape( + grid_t, + num_windows_h * num_windows_w, + vit_merger_window_size, + vit_merger_window_size, + ) + seqlens = (index_padded != -100).sum([2, 3]).reshape(-1) + index_padded = index_padded.reshape(-1) + index_new = index_padded[index_padded != -100] + window_index.append(index_new + window_index_id) + cu_seqlens_tmp = seqlens.cumsum(0) * self.spatial_merge_unit + cu_window_seqlens[-1] + cu_window_seqlens.extend(cu_seqlens_tmp.tolist()) + window_index_id += grid_t * llm_grid_h * llm_grid_w + window_index = torch.cat(window_index, dim=0) + + return window_index, cu_window_seqlens + + @merge_with_config_defaults + @capture_outputs + def forward( + self, hidden_states: torch.Tensor, grid_thw: torch.Tensor, **kwargs: Unpack[TransformersKwargs] + ) -> tuple | BaseModelOutputWithPooling: + """ + Args: + hidden_states (`torch.Tensor` of shape `(seq_len, hidden_size)`): + The final hidden states of the model. + grid_thw (`torch.Tensor` of shape `(num_images_or_videos, 3)`): + The temporal, height and width of feature shape of each image in LLM. + + Returns: + `torch.Tensor`: hidden_states. + """ + hidden_states = self.patch_embed(hidden_states) + rotary_pos_emb = self.rot_pos_emb(grid_thw) + window_index, cu_window_seqlens = self.get_window_index(grid_thw) + cu_window_seqlens = torch.tensor( + cu_window_seqlens, + device=hidden_states.device, + dtype=grid_thw.dtype if torch.jit.is_tracing() else torch.int32, + ) + cu_window_seqlens = torch.unique_consecutive(cu_window_seqlens) + + seq_len, _ = hidden_states.size() + hidden_states = hidden_states.reshape(seq_len // self.spatial_merge_unit, self.spatial_merge_unit, -1) + hidden_states = hidden_states[window_index, :, :] + hidden_states = hidden_states.reshape(seq_len, -1) + rotary_pos_emb = rotary_pos_emb.reshape(seq_len // self.spatial_merge_unit, self.spatial_merge_unit, -1) + rotary_pos_emb = rotary_pos_emb[window_index, :, :] + rotary_pos_emb = rotary_pos_emb.reshape(seq_len, -1) + emb = torch.cat((rotary_pos_emb, rotary_pos_emb), dim=-1) + position_embeddings = (emb.cos(), emb.sin()) + + cu_seqlens = torch.repeat_interleave(grid_thw[:, 1] * grid_thw[:, 2], grid_thw[:, 0]).cumsum( + dim=0, + # Select dtype based on the following factors: + # - FA2 requires that cu_seqlens_q must have dtype int32 + # - torch.onnx.export requires that cu_seqlens_q must have same dtype as grid_thw + # See https://github.com/huggingface/transformers/pull/34852 for more information + dtype=grid_thw.dtype if torch.jit.is_tracing() else torch.int32, + ) + cu_seqlens = F.pad(cu_seqlens, (1, 0), value=0) + + for layer_num, blk in enumerate(self.blocks): + if layer_num in self.fullatt_block_indexes: + cu_seqlens_now = cu_seqlens + else: + cu_seqlens_now = cu_window_seqlens + + hidden_states = blk( + hidden_states, + cu_seqlens=cu_seqlens_now, + position_embeddings=position_embeddings, + **kwargs, + ) + + merged_hidden_states = self.merger(hidden_states) + reverse_indices = torch.argsort(window_index) + merged_hidden_states = merged_hidden_states[reverse_indices, :] + + return BaseModelOutputWithPooling( + last_hidden_state=hidden_states, + pooler_output=merged_hidden_states, + ) + + +@dataclass +@auto_docstring( + custom_intro=""" + Base class for Llava outputs, with hidden states and attentions. + """ +) +class Qwen2_5_VLModelOutputWithPast(ModelOutput): + r""" + past_key_values (`Cache`, *optional*, returned when `use_cache=True` is passed or when `config.use_cache=True`): + It is a [`~cache_utils.Cache`] instance. For more details, see our [kv cache guide](https://huggingface.co/docs/transformers/en/kv_cache). + + Contains pre-computed hidden-states (key and values in the self-attention blocks) that can be used (see + `past_key_values` input) to speed up sequential decoding. + rope_deltas (`torch.LongTensor` of shape `(batch_size, )`, *optional*): + The rope index difference between sequence length and multimodal rope. + """ + + last_hidden_state: torch.FloatTensor | None = None + past_key_values: Cache | None = None + hidden_states: tuple[torch.FloatTensor] | None = None + attentions: tuple[torch.FloatTensor] | None = None + rope_deltas: torch.LongTensor | None = None + + +class Qwen2_5_VLRotaryEmbedding(nn.Module): + inv_freq: torch.Tensor # fix linting for `register_buffer` + + def __init__(self, config: Qwen2_5_VLConfig, device=None): + super().__init__() + self.max_seq_len_cached = config.max_position_embeddings + self.original_max_seq_len = config.max_position_embeddings + + self.config = config + + self.rope_type = self.config.rope_parameters["rope_type"] + rope_init_fn: Callable = self.compute_default_rope_parameters + if self.rope_type != "default": + rope_init_fn = ROPE_INIT_FUNCTIONS[self.rope_type] + inv_freq, self.attention_scaling = rope_init_fn(self.config, device) + + self.register_buffer("inv_freq", inv_freq, persistent=False) + self.register_buffer("original_inv_freq", inv_freq.clone(), persistent=False) + + @staticmethod + def compute_default_rope_parameters( + config: Qwen2_5_VLConfig | None = None, + device: Optional["torch.device"] = None, + seq_len: int | None = None, + ) -> tuple["torch.Tensor", float]: + """ + Computes the inverse frequencies according to the original RoPE implementation + Args: + config ([`~transformers.PreTrainedConfig`]): + The model configuration. + device (`torch.device`): + The device to use for initialization of the inverse frequencies. + seq_len (`int`, *optional*): + The current sequence length. Unused for this type of RoPE. + Returns: + Tuple of (`torch.Tensor`, `float`), containing the inverse frequencies for the RoPE embeddings and the + post-processing scaling factor applied to the computed cos/sin (unused in this type of RoPE). + """ + base = config.rope_parameters["rope_theta"] + dim = getattr(config, "head_dim", None) or config.hidden_size // config.num_attention_heads + + attention_factor = 1.0 # Unused in this type of RoPE + + # Compute the inverse frequencies + inv_freq = 1.0 / ( + base ** (torch.arange(0, dim, 2, dtype=torch.int64).to(device=device, dtype=torch.float) / dim) + ) + return inv_freq, attention_factor + + # Ignore copy + def forward(self, x, position_ids): + # In contrast to other models, Qwen2_5_VL has different position ids for the grids + # So we expand the inv_freq to shape (3, ...) + inv_freq_expanded = self.inv_freq[None, None, :, None].float().expand(3, position_ids.shape[1], -1, 1) + position_ids_expanded = position_ids[:, :, None, :].float() # shape (3, bs, 1, positions) + + device_type = x.device.type if isinstance(x.device.type, str) and x.device.type != "mps" else "cpu" + with maybe_autocast(device_type=device_type, enabled=False): # Force float32 + freqs = (inv_freq_expanded.float() @ position_ids_expanded.float()).transpose(2, 3) + emb = torch.cat((freqs, freqs), dim=-1) + cos = emb.cos() * self.attention_scaling + sin = emb.sin() * self.attention_scaling + + return cos.to(dtype=x.dtype), sin.to(dtype=x.dtype) + + +class Qwen2MLP(nn.Module): + def __init__(self, config): + super().__init__() + self.config = config + self.hidden_size = config.hidden_size + self.intermediate_size = config.intermediate_size + self.gate_proj = nn.Linear(self.hidden_size, self.intermediate_size, bias=False) + self.up_proj = nn.Linear(self.hidden_size, self.intermediate_size, bias=False) + self.down_proj = nn.Linear(self.intermediate_size, self.hidden_size, bias=False) + self.act_fn = ACT2FN[config.hidden_act] + + def forward(self, x): + down_proj = self.down_proj(self.act_fn(self.gate_proj(x)) * self.up_proj(x)) + return down_proj + + +def apply_multimodal_rotary_pos_emb(q, k, cos, sin, mrope_section, unsqueeze_dim=1): + """Applies Rotary Position Embedding with Multimodal Sections to the query and key tensors (https://qwenlm.github.io/blog/qwen2-vl/). + + Explanation: + Multimodal 3D rotary position embedding is an extension to 1D rotary position embedding. The input embedding + sequence contains vision (images / videos) embedding and text embedding or just contains text embedding. For + vision embedding part, we apply rotary position embedding on temporal, height and width dimension separately. + Here we split the channel dimension to 3 chunks for the temporal, height and width rotary position embedding. + For text embedding part, we just apply 1D rotary position embedding. The three rotary position index (temporal, + height and width) of text embedding is always the same, so the text embedding rotary position embedding has no + difference with modern LLMs. + + Args: + q (`torch.Tensor`): The query tensor. + k (`torch.Tensor`): The key tensor. + cos (`torch.Tensor`): The cosine part of the rotary embedding. + sin (`torch.Tensor`): The sine part of the rotary embedding. + position_ids (`torch.Tensor`): + The position indices of the tokens corresponding to the query and key tensors. For example, this can be + used to pass offsetted position ids when working with a KV-cache. + mrope_section(`List(int)`): + Multimodal rope section is for channel dimension of temporal, height and width in rope calculation. + unsqueeze_dim (`int`, *optional*, defaults to 1): + The 'unsqueeze_dim' argument specifies the dimension along which to unsqueeze cos[position_ids] and + sin[position_ids] so that they can be properly broadcasted to the dimensions of q and k. For example, note + that cos[position_ids] and sin[position_ids] have the shape [batch_size, seq_len, head_dim]. Then, if q and + k have the shape [batch_size, heads, seq_len, head_dim], then setting unsqueeze_dim=1 makes + cos[position_ids] and sin[position_ids] broadcastable to the shapes of q and k. Similarly, if q and k have + the shape [batch_size, seq_len, heads, head_dim], then set unsqueeze_dim=2. + Returns: + `tuple(torch.Tensor)` comprising of the query and key tensors rotated using the Rotary Position Embedding. + """ + mrope_section = mrope_section * 2 + cos = torch.cat([m[i % 3] for i, m in enumerate(cos.split(mrope_section, dim=-1))], dim=-1).unsqueeze( + unsqueeze_dim + ) + sin = torch.cat([m[i % 3] for i, m in enumerate(sin.split(mrope_section, dim=-1))], dim=-1).unsqueeze( + unsqueeze_dim + ) + + q_embed = (q * cos) + (rotate_half(q) * sin) + k_embed = (k * cos) + (rotate_half(k) * sin) + return q_embed, k_embed + + +class Qwen2_5_VLAttention(nn.Module): + """ + Multi-headed attention from 'Attention Is All You Need' paper. Modified to use sliding window attention: Longformer + and "Generating Long Sequences with Sparse Transformers". + """ + + def __init__(self, config: Qwen2_5_VLTextConfig, layer_idx: int | None = None): + super().__init__() + self.config = config + self.layer_idx = layer_idx + if layer_idx is None: + logger.warning_once( + f"Instantiating {self.__class__.__name__} without passing `layer_idx` is not recommended and will " + "to errors during the forward call, if caching is used. Please make sure to provide a `layer_idx` " + "when creating this class." + ) + + self.hidden_size = config.hidden_size + self.num_heads = config.num_attention_heads + self.head_dim = self.hidden_size // self.num_heads + self.num_key_value_heads = config.num_key_value_heads + self.num_key_value_groups = self.num_heads // self.num_key_value_heads + self.is_causal = True + self.attention_dropout = config.attention_dropout + self.rope_parameters = config.rope_parameters + self.scaling = self.head_dim**-0.5 + + if (self.head_dim * self.num_heads) != self.hidden_size: + raise ValueError( + f"hidden_size must be divisible by num_heads (got `hidden_size`: {self.hidden_size}" + f" and `num_heads`: {self.num_heads})." + ) + self.q_proj = nn.Linear(self.hidden_size, self.num_heads * self.head_dim, bias=True) + self.k_proj = nn.Linear(self.hidden_size, self.num_key_value_heads * self.head_dim, bias=True) + self.v_proj = nn.Linear(self.hidden_size, self.num_key_value_heads * self.head_dim, bias=True) + self.o_proj = nn.Linear(self.num_heads * self.head_dim, self.hidden_size, bias=False) + self.layer_type = config.layer_types[layer_idx] if hasattr(config, "layer_types") else None + self.sliding_window = config.sliding_window if self.layer_type == "sliding_attention" else None + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.Tensor | None = None, + position_ids: torch.LongTensor | None = None, + past_key_values: Cache | None = None, + output_attentions: bool = False, + use_cache: bool = False, + cache_position: torch.LongTensor | None = None, + position_embeddings: tuple[torch.Tensor, torch.Tensor] | None = None, + **kwargs: Unpack[FlashAttentionKwargs], + ) -> tuple[torch.Tensor, torch.Tensor | None, tuple[torch.Tensor] | None]: + bsz, q_len, _ = hidden_states.size() + + query_states = self.q_proj(hidden_states) + key_states = self.k_proj(hidden_states) + value_states = self.v_proj(hidden_states) + + query_states = query_states.view(bsz, q_len, -1, self.head_dim).transpose(1, 2) + key_states = key_states.view(bsz, q_len, -1, self.head_dim).transpose(1, 2) + value_states = value_states.view(bsz, q_len, -1, self.head_dim).transpose(1, 2) + + cos, sin = position_embeddings + query_states, key_states = apply_multimodal_rotary_pos_emb( + query_states, key_states, cos, sin, self.config.rope_parameters["mrope_section"] + ) + + if past_key_values is not None: + cache_kwargs = {"sin": sin, "cos": cos, "cache_position": cache_position} # Specific to RoPE models + key_states, value_states = past_key_values.update(key_states, value_states, self.layer_idx, cache_kwargs) + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, eager_attention_forward + ) + + attn_output, attn_weights = attention_interface( + self, + query_states, + key_states, + value_states, + attention_mask, + dropout=0.0 if not self.training else self.attention_dropout, + scaling=self.scaling, + sliding_window=self.sliding_window, + position_ids=position_ids, # pass positions for FA2 + **kwargs, + ) + + attn_output = attn_output.reshape(bsz, q_len, -1).contiguous() + attn_output = self.o_proj(attn_output) + return attn_output, attn_weights + + +class Qwen2_5_VLDecoderLayer(GradientCheckpointingLayer): + def __init__(self, config: Qwen2_5_VLTextConfig, layer_idx: int): + super().__init__() + self.hidden_size = config.hidden_size + + if config.use_sliding_window and not is_flash_attention_requested(config): + logger.warning_once( + f"Sliding Window Attention is enabled but not implemented for `{config._attn_implementation}`; " + "unexpected results may be encountered." + ) + self.self_attn = Qwen2_5_VLAttention(config, layer_idx) + + self.mlp = Qwen2MLP(config) + self.input_layernorm = Qwen2_5_VLRMSNorm(config.hidden_size, eps=config.rms_norm_eps) + self.post_attention_layernorm = Qwen2_5_VLRMSNorm(config.hidden_size, eps=config.rms_norm_eps) + self.attention_type = config.layer_types[layer_idx] + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.Tensor | None = None, + position_ids: torch.LongTensor | None = None, + past_key_values: Cache | None = None, + output_attentions: bool | None = False, + use_cache: bool | None = False, + cache_position: torch.LongTensor | None = None, + position_embeddings: tuple[torch.Tensor, torch.Tensor] | None = None, + **kwargs: Unpack[FlashAttentionKwargs], + ) -> tuple[torch.FloatTensor, tuple[torch.FloatTensor, torch.FloatTensor] | None]: + """ + Args: + hidden_states (`torch.FloatTensor`): input to the layer of shape `(batch, seq_len, embed_dim)` + attention_mask (`torch.FloatTensor`, *optional*): attention mask of size + `(batch, sequence_length)` where padding elements are indicated by 0. + output_attentions (`bool`, *optional*): + Whether or not to return the attentions tensors of all attention layers. See `attentions` under + returned tensors for more detail. + use_cache (`bool`, *optional*): + If set to `True`, `past_key_values` key value states are returned and can be used to speed up decoding + (see `past_key_values`). + past_key_values (`Cache`, *optional*): cached past key and value projection states + cache_position (`torch.LongTensor` of shape `(sequence_length)`, *optional*): + Indices depicting the position of the input sequence tokens in the sequence. + position_embeddings (`tuple[torch.FloatTensor, torch.FloatTensor]`, *optional*): + Tuple containing the cosine and sine positional embeddings of shape `(batch_size, seq_len, head_dim)`, + with `head_dim` being the embedding dimension of each attention head. + kwargs (`dict`, *optional*): + Arbitrary kwargs to be ignored, used for FSDP and other methods that injects code + into the model + """ + + residual = hidden_states + + hidden_states = self.input_layernorm(hidden_states) + + # Self Attention + hidden_states, self_attn_weights = self.self_attn( + hidden_states=hidden_states, + attention_mask=attention_mask, + position_ids=position_ids, + past_key_values=past_key_values, + output_attentions=output_attentions, + use_cache=use_cache, + cache_position=cache_position, + position_embeddings=position_embeddings, + **kwargs, + ) + hidden_states = residual + hidden_states + + # Fully Connected + residual = hidden_states + hidden_states = self.post_attention_layernorm(hidden_states) + hidden_states = self.mlp(hidden_states) + hidden_states = residual + hidden_states + + outputs = (hidden_states,) + + if output_attentions: + outputs += (self_attn_weights,) + + return outputs + + +@auto_docstring +class Qwen2_5_VLTextModel(Qwen2_5_VLPreTrainedModel): + config: Qwen2_5_VLTextConfig + input_modalities = ("text",) + + def __init__(self, config: Qwen2_5_VLTextConfig): + super().__init__(config) + self.padding_idx = config.pad_token_id + self.vocab_size = config.vocab_size + + self.embed_tokens = nn.Embedding(config.vocab_size, config.hidden_size, self.padding_idx) + self.layers = nn.ModuleList( + [Qwen2_5_VLDecoderLayer(config, layer_idx) for layer_idx in range(config.num_hidden_layers)] + ) + self._attn_implementation = config._attn_implementation + self.norm = Qwen2_5_VLRMSNorm(config.hidden_size, eps=config.rms_norm_eps) + self.has_sliding_layers = "sliding_attention" in self.config.layer_types + self.rotary_emb = Qwen2_5_VLRotaryEmbedding(config=config) + + self.gradient_checkpointing = False + # Initialize weights and apply final processing + self.post_init() + + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.Tensor | None = None, + position_ids: torch.LongTensor | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.FloatTensor | None = None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + cache_position: torch.LongTensor | None = None, + **kwargs: Unpack[FlashAttentionKwargs], + ) -> tuple | BaseModelOutputWithPast: + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + use_cache = use_cache if use_cache is not None else self.config.use_cache + + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + if (input_ids is None) ^ (inputs_embeds is not None): + raise ValueError("You must specify exactly one of input_ids or inputs_embeds") + + if self.gradient_checkpointing and self.training: + if use_cache: + logger.warning_once( + "`use_cache=True` is incompatible with gradient checkpointing. Setting `use_cache=False`..." + ) + use_cache = False + + # torch.jit.trace() doesn't support cache objects in the output + if use_cache and past_key_values is None and not torch.jit.is_tracing(): + past_key_values = DynamicCache(config=self.config) + + if inputs_embeds is None: + inputs_embeds = self.embed_tokens(input_ids) + + if cache_position is None: + past_seen_tokens = past_key_values.get_seq_length() if past_key_values is not None else 0 + cache_position = torch.arange( + past_seen_tokens, past_seen_tokens + inputs_embeds.shape[1], device=inputs_embeds.device + ) + + # the hard coded `3` is for temporal, height and width. + if position_ids is None: + position_ids = cache_position.view(1, 1, -1).expand(3, inputs_embeds.shape[0], -1) + elif position_ids.ndim == 2: + position_ids = position_ids[None, ...].expand(3, position_ids.shape[0], -1) + + # NOTE: we need to pass text position ids for packing. Qwen2-VL uses 3D positions + # where each dim indicates visual spatial positions for temporal/height/width grids. + # There are two scenarios when FA2-like packed masking might be activated. + # 1. User specifically passed packed `position_ids` and no attention mask. + # In this case we expect the useer to create correct position ids for all 3 grids + # and prepend text-only position ids to it. The final tensor will be [4, bs, seq-len] + # 2. User runs forward with no attention mask and no position ids. In this case, position ids + # are prepared by the model (`get_rope_index`) as `[4, bs, seq-len]` tensor. Text-only positions are + # prepended by us when creating positions so that the mask is constructed correctly. NOTE: failing to pass + # text-only positions will cause incorrect mask construction, do not change `prepare_input_for_generation` + if position_ids.ndim == 3 and position_ids.shape[0] == 4: + text_position_ids = position_ids[0] + position_ids = position_ids[1:] + else: + # If inputs are not packed (usual 3D positions), do not prepare mask from position_ids + text_position_ids = None + + # It may already have been prepared by e.g. `generate` + if not isinstance(causal_mask_mapping := attention_mask, dict): + # Prepare mask arguments + mask_kwargs = { + "config": self.config, + "inputs_embeds": inputs_embeds, + "attention_mask": attention_mask, + "cache_position": cache_position, + "past_key_values": past_key_values, + "position_ids": text_position_ids, + } + # Create the masks + causal_mask_mapping = { + "full_attention": create_causal_mask(**mask_kwargs), + } + # The sliding window alternating layers are not always activated depending on the config + if self.has_sliding_layers: + causal_mask_mapping["sliding_attention"] = create_sliding_window_causal_mask(**mask_kwargs) + + hidden_states = inputs_embeds + position_embeddings = self.rotary_emb(hidden_states, position_ids) + + # decoder layers + all_hidden_states = () if output_hidden_states else None + all_self_attns = () if output_attentions else None + + for decoder_layer in self.layers: + if output_hidden_states: + all_hidden_states += (hidden_states,) + + layer_outputs = decoder_layer( + hidden_states, + attention_mask=causal_mask_mapping[decoder_layer.attention_type], + position_embeddings=position_embeddings, + position_ids=text_position_ids, + past_key_values=past_key_values, + output_attentions=output_attentions, + use_cache=use_cache, + cache_position=cache_position, + **kwargs, + ) + + hidden_states = layer_outputs[0] + + if output_attentions: + all_self_attns += (layer_outputs[1],) + + hidden_states = self.norm(hidden_states) + + # add hidden states from the last decoder layer + if output_hidden_states: + all_hidden_states += (hidden_states,) + + if not return_dict: + return tuple( + v for v in [hidden_states, past_key_values, all_hidden_states, all_self_attns] if v is not None + ) + return BaseModelOutputWithPast( + last_hidden_state=hidden_states, + past_key_values=past_key_values, + hidden_states=all_hidden_states, + attentions=all_self_attns, + ) + + +@auto_docstring +class Qwen2_5_VLModel(Qwen2_5_VLPreTrainedModel): + base_model_prefix = "model" + _checkpoint_conversion_mapping = {"^model": "language_model"} + # Reference: fix gemma3 grad acc #37208 + accepts_loss_kwargs = False + config: Qwen2_5_VLConfig + _no_split_modules = ["Qwen2_5_VLDecoderLayer", "Qwen2_5_VLVisionBlock"] + + def __init__(self, config): + super().__init__(config) + self.visual = Qwen2_5_VisionTransformerPretrainedModel._from_config(config.vision_config) + self.language_model = Qwen2_5_VLTextModel._from_config(config.text_config) + self.rope_deltas = None # cache rope_deltas here + + # Initialize weights and apply final processing + self.post_init() + + def get_input_embeddings(self): + return self.language_model.get_input_embeddings() + + def set_input_embeddings(self, value): + self.language_model.set_input_embeddings(value) + + def get_vision_position_ids( + self, + start_position: int, + grid_thw: list[int, int, int] | torch.Tensor, + temp_merge_size: int = 1, + spatial_merge_size: int = 1, + time_interval: int = 1, + device: str | torch.device | None = None, + ): + """ + Compute 3D positional indices for vision tokens derived from a single image or video input. + + The positions are generated from the input grid defined by temporal (T), height (H), and + width (W) dimensions. Temporal and spatial dimensions can be downscaled according to the + merge sizes used in the vision backbone. The resulting positions are offset by `start_position`. + + Args: + start_position (`int`): + Offset added to all computed positional indices. + grid_thw (`Sequence[int]` or `torch.Tensor` of shape `(3,)`): + The (T, H, W) grid representing the feature layout of the current image or video after patch embedding. + temp_merge_size (`int`, *optional*): + Factor by which the temporal dimension is reduced in the backbone. The temporal grid size is divided + by this value. Defaults to 1. + spatial_merge_size (`int`, *optional*): + Factor by which the spatial dimensions (H and W) are reduced in the backbone. Both H and W are divided + by this value. Defaults to 1. + time_interval (`int`, *optional*): + Spacing factor applied between consecutive temporal position indices.Defaults to 1. + device (`str` or `torch.device`, *optional*): + Device on which the resulting tensor is allocated. If `None`, uses the current default device. + + Returns: + torch.LongTensor of shape (3, sequence_length): + Positional indices for temporal, height, and width dimensions, + flattened into sequence form and offset by `start_position`. + """ + llm_grid_t, llm_grid_h, llm_grid_w = ( + grid_thw[0].item() // temp_merge_size, + grid_thw[1].item() // spatial_merge_size, + grid_thw[2].item() // spatial_merge_size, + ) + + image_seq_length = llm_grid_h * llm_grid_w * llm_grid_t + position_width = torch.arange(start_position, start_position + llm_grid_w, device=device).repeat( + llm_grid_h * llm_grid_t + ) + position_height = torch.arange(start_position, start_position + llm_grid_h, device=device).repeat_interleave( + llm_grid_w * llm_grid_t + ) + position_temporal = torch.full((image_seq_length,), start_position, device=device, dtype=torch.long) + position_temporal = position_temporal * time_interval + vision_position_ids = torch.stack([position_temporal, position_height, position_width], dim=0) + + return vision_position_ids + + def get_rope_index( + self, + input_ids: torch.LongTensor, + mm_token_type_ids: torch.IntTensor, + image_grid_thw: torch.LongTensor | None = None, + video_grid_thw: torch.LongTensor | None = None, + second_per_grid_ts: torch.Tensor | None = None, + attention_mask: torch.Tensor | None = None, + **kwargs, + ) -> tuple[torch.Tensor, torch.Tensor]: + """ + Calculate the 3D rope index based on image and video's sizes. The utility expects a `vision + text` + sequence and will error out otherwise. For pure text sequence, please rely on model's auto-inferred + position ids. In a mixed vision + text sequence, vision tokens use 3D RoPE (temporal, height, width) + while text tokens use standard 1D RoPE. + + Example: + Temporal patches: 3; Height patches: 2; Width patches: 2 + Each vision input results in (temporal x height × width) positions. Here: 3 x 2 × 2 = 12 positions total. + + Temporal position IDs are spaced by: + `interval = tokens_per_second * temporal_patch_size / fps` + + If fps = 1; tokens_per_second = 25; temporal_patch_size = 2, temporal IDs increase by 50 for each temporal patch: + `[0, 0, 0, 0, 50, 50, 50, 50, 100, 100, 100, 100]` + + Height IDs repeat per row: `[0, 0, 1, 1, ...]` + Width IDs alternate per column: `[0, 1, 0, 1, ...]` + Text tokens follow standard 1D RoPE and the position IDs grow consequently with a step of `1` + + Args: + input_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`): + Indices of input sequence tokens in the vocabulary. Padding will be ignored by default should you provide + it. + mm_token_type_ids (`torch.IntTensor` of shape `(batch_size, sequence_length)`): + Token type ids matching each modality to a different value in the input sequence, i.e. text (0), image (1), video (2). + image_grid_thw (`torch.LongTensor` of shape `(num_images, 3)`, *optional*): + The temporal, height and width of feature shape of each image in LLM. + video_grid_thw (`torch.LongTensor` of shape `(num_videos, 3)`, *optional*): + The temporal, height and width of feature shape of each video in LLM. + second_per_grid_ts (`torch.Tensor` of shape `(num_videos)`, *optional*): + The time interval (in seconds) for each grid along the temporal dimension in the 3D position IDs. + attention_mask (`torch.Tensor` of shape `(batch_size, sequence_length)`, *optional*): + Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`: + + - 1 for tokens that are **not masked**, + - 0 for tokens that are **masked**. + + Returns: + position_ids (`torch.LongTensor` of shape `(3, batch_size, sequence_length)`) + mrope_position_deltas (`torch.Tensor` of shape `(batch_size)`) + """ + spatial_merge_size = self.config.vision_config.spatial_merge_size + tokens_per_second = self.config.vision_config.tokens_per_second + + mrope_position_deltas = [] + position_ids = torch.zeros( + 3, + input_ids.shape[0], + input_ids.shape[1], + dtype=input_ids.dtype, + device=input_ids.device, + ) + grid_iters = { + 1: iter(image_grid_thw) if image_grid_thw is not None else None, + 2: iter(video_grid_thw) if video_grid_thw is not None else None, + } + second_per_grid_ts = ( + iter(second_per_grid_ts) if second_per_grid_ts is not None else iter([1] * input_ids.shape[1]) + ) + for batch_idx, current_input_ids in enumerate(input_ids): + input_token_type = mm_token_type_ids[batch_idx] + if attention_mask is not None: + current_input_ids = current_input_ids[attention_mask[batch_idx].bool()] + input_token_type = input_token_type[attention_mask[batch_idx].bool()] + + input_type_group = [] + for key, group in itertools.groupby(enumerate(input_token_type.tolist()), lambda x: x[1]): + group = list(group) + start_index = group[0][0] + end_index = group[-1][0] + 1 + input_type_group.append((key, start_index, end_index)) + + current_pos = 0 + llm_pos_ids_list = [] + for modality_type, start_idx, end_idx in input_type_group: + # text == 0 + if modality_type == 0: + text_len = end_idx - start_idx + llm_pos_ids_list.append( + torch.arange(text_len, device=input_ids.device).view(1, -1).expand(3, -1) + current_pos + ) + current_pos += text_len + # image == 1, video == 2 + else: + grid_thw = next(grid_iters[modality_type]) + time_interval = tokens_per_second * int(next(second_per_grid_ts)) + vision_position_ids = self.get_vision_position_ids( + current_pos, grid_thw, 1, spatial_merge_size, time_interval, device=input_ids.device + ) + llm_pos_ids_list.append(vision_position_ids) + current_pos += max(grid_thw[1], grid_thw[2]) // spatial_merge_size + llm_positions = torch.cat(llm_pos_ids_list, dim=1).reshape(3, -1) + if attention_mask is not None: + position_ids[:, batch_idx, attention_mask[batch_idx].bool()] = llm_positions.to(position_ids.device) + else: + position_ids[:, batch_idx] = llm_positions.to(position_ids.device) + mrope_position_deltas.append(llm_positions.max() + 1 - len(current_input_ids)) + mrope_position_deltas = torch.tensor(mrope_position_deltas, device=input_ids.device).unsqueeze(1) + return position_ids, mrope_position_deltas + + @can_return_tuple + @auto_docstring + def get_video_features( + self, + pixel_values_videos: torch.FloatTensor, + video_grid_thw: torch.LongTensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple | BaseModelOutputWithPooling: + r""" + pixel_values_videos (`torch.FloatTensor` of shape `(batch_size, num_channels, image_size, image_size)`): + The tensors corresponding to the input videos. + video_grid_thw (`torch.LongTensor` of shape `(num_videos, 3)`, *optional*): + The temporal, height and width of feature shape of each video in LLM. + """ + pixel_values_videos = pixel_values_videos.type(self.visual.dtype) + vision_outputs = self.visual(pixel_values_videos, grid_thw=video_grid_thw, return_dict=True, **kwargs) + split_sizes = (video_grid_thw.prod(-1) // self.visual.spatial_merge_size**2).tolist() + video_embeds = torch.split(vision_outputs.pooler_output, split_sizes) + vision_outputs.pooler_output = video_embeds + + return vision_outputs + + @can_return_tuple + @auto_docstring + def get_image_features( + self, + pixel_values: torch.FloatTensor, + image_grid_thw: torch.LongTensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple | BaseModelOutputWithPooling: + r""" + pixel_values (`torch.FloatTensor` of shape `(batch_size, num_channels, image_size, image_size)`): + The tensors corresponding to the input images. + image_grid_thw (`torch.LongTensor` of shape `(num_images, 3)`, *optional*): + The temporal, height and width of feature shape of each image in LLM. + """ + pixel_values = pixel_values.type(self.visual.dtype) + vision_outputs = self.visual(pixel_values, grid_thw=image_grid_thw, return_dict=True, **kwargs) + split_sizes = (image_grid_thw.prod(-1) // self.visual.spatial_merge_size**2).tolist() + image_embeds = torch.split(vision_outputs.pooler_output, split_sizes) + vision_outputs.pooler_output = image_embeds + + return vision_outputs + + def get_placeholder_mask( + self, + input_ids: torch.LongTensor, + inputs_embeds: torch.FloatTensor, + image_features: torch.FloatTensor | None = None, + video_features: torch.FloatTensor | None = None, + ): + """ + Obtains multimodal placeholder mask from `input_ids` or `inputs_embeds`, and checks that the placeholder token count is + equal to the length of multimodal features. If the lengths are different, an error is raised. + """ + if input_ids is None: + special_image_mask = inputs_embeds == self.get_input_embeddings()( + torch.tensor(self.config.image_token_id, dtype=torch.long, device=inputs_embeds.device) + ) + special_image_mask = special_image_mask.all(-1) + special_video_mask = inputs_embeds == self.get_input_embeddings()( + torch.tensor(self.config.video_token_id, dtype=torch.long, device=inputs_embeds.device) + ) + special_video_mask = special_video_mask.all(-1) + else: + special_image_mask = input_ids == self.config.image_token_id + special_video_mask = input_ids == self.config.video_token_id + + n_image_tokens = special_image_mask.sum() + special_image_mask = special_image_mask.unsqueeze(-1).expand_as(inputs_embeds).to(inputs_embeds.device) + if image_features is not None: + torch_compilable_check( + inputs_embeds[special_image_mask].numel() == image_features.numel(), + f"Image features and image tokens do not match, tokens: {n_image_tokens}, features: {image_features.shape[0]}", + ) + + n_video_tokens = special_video_mask.sum() + special_video_mask = special_video_mask.unsqueeze(-1).expand_as(inputs_embeds).to(inputs_embeds.device) + if video_features is not None: + torch_compilable_check( + inputs_embeds[special_video_mask].numel() == video_features.numel(), + f"Video features and video tokens do not match, tokens: {n_video_tokens}, features: {video_features.shape[0]}", + ) + return special_image_mask, special_video_mask + + def compute_3d_position_ids( + self, + input_ids: torch.Tensor | None, + image_grid_thw: torch.Tensor | None, + video_grid_thw: torch.Tensor | None, + inputs_embeds: torch.Tensor | None, + attention_mask: torch.Tensor | None, + past_key_values: torch.Tensor | None, + second_per_grid_ts: torch.Tensor | None = None, + mm_token_type_ids: torch.IntTensor | None = None, + ) -> torch.Tensor | None: + past_key_values_length = 0 if past_key_values is None else past_key_values.get_seq_length() + can_compute_mrope = ( + input_ids is not None + and mm_token_type_ids is not None + and (image_grid_thw is not None or video_grid_thw is not None) + ) + + if can_compute_mrope and (self.rope_deltas is None or past_key_values_length == 0): + position_ids, rope_deltas = self.get_rope_index( + input_ids, + image_grid_thw=image_grid_thw, + video_grid_thw=video_grid_thw, + attention_mask=attention_mask, + second_per_grid_ts=second_per_grid_ts, + mm_token_type_ids=mm_token_type_ids, + ) + self.rope_deltas = rope_deltas + # Use pre-calculated rope-deltas to infer correct 3D position ids + elif self.rope_deltas is not None: + batch_size, seq_length, _ = inputs_embeds.shape + if attention_mask is not None: + position_ids = attention_mask.long().cumsum(-1) - 1 + position_ids = position_ids.masked_fill(attention_mask == 0, 0) + position_ids = position_ids.view(1, batch_size, -1).repeat(3, 1, 1).to(inputs_embeds.device) + else: + position_ids = torch.arange(past_key_values_length, past_key_values_length + seq_length) + position_ids = position_ids.view(1, 1, -1).expand(3, batch_size, -1).to(inputs_embeds.device) + delta = self.rope_deltas.repeat_interleave(batch_size // self.rope_deltas.shape[0], dim=0) + position_ids = position_ids + delta.to(device=position_ids.device) + else: + # Can't build correct 3D positions. Let the model infer it from `cache_position` + position_ids = None + return position_ids + + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.Tensor | None = None, + position_ids: torch.LongTensor | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.FloatTensor | None = None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + pixel_values: torch.Tensor | None = None, + pixel_values_videos: torch.FloatTensor | None = None, + image_grid_thw: torch.LongTensor | None = None, + video_grid_thw: torch.LongTensor | None = None, + rope_deltas: torch.LongTensor | None = None, + mm_token_type_ids: torch.IntTensor | None = None, + cache_position: torch.LongTensor | None = None, + second_per_grid_ts: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple | Qwen2_5_VLModelOutputWithPast: + r""" + image_grid_thw (`torch.LongTensor` of shape `(num_images, 3)`, *optional*): + The temporal, height and width of feature shape of each image in LLM. + video_grid_thw (`torch.LongTensor` of shape `(num_videos, 3)`, *optional*): + The temporal, height and width of feature shape of each video in LLM. + rope_deltas (`torch.LongTensor` of shape `(batch_size, )`, *optional*): + The rope index difference between sequence length and multimodal rope. + second_per_grid_ts (`torch.Tensor` of shape `(num_videos)`, *optional*): + The time interval (in seconds) for each grid along the temporal dimension in the 3D position IDs. + """ + + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + if inputs_embeds is None: + inputs_embeds = self.get_input_embeddings()(input_ids) + + if pixel_values is not None: + image_embeds = self.get_image_features(pixel_values, image_grid_thw, return_dict=True).pooler_output + image_embeds = torch.cat(image_embeds, dim=0).to(inputs_embeds.device, inputs_embeds.dtype) + image_mask, _ = self.get_placeholder_mask( + input_ids, inputs_embeds=inputs_embeds, image_features=image_embeds + ) + inputs_embeds = inputs_embeds.masked_scatter(image_mask, image_embeds) + + if pixel_values_videos is not None: + video_embeds = self.get_video_features(pixel_values_videos, video_grid_thw, return_dict=True).pooler_output + video_embeds = torch.cat(video_embeds, dim=0).to(inputs_embeds.device, inputs_embeds.dtype) + _, video_mask = self.get_placeholder_mask( + input_ids, inputs_embeds=inputs_embeds, video_features=video_embeds + ) + inputs_embeds = inputs_embeds.masked_scatter(video_mask, video_embeds) + + if position_ids is None: + position_ids = self.compute_3d_position_ids( + input_ids=input_ids, + image_grid_thw=image_grid_thw, + video_grid_thw=video_grid_thw, + second_per_grid_ts=second_per_grid_ts, + inputs_embeds=inputs_embeds, + attention_mask=attention_mask, + past_key_values=past_key_values, + mm_token_type_ids=mm_token_type_ids, + ) + + outputs = self.language_model( + input_ids=None, + position_ids=position_ids, + attention_mask=attention_mask, + past_key_values=past_key_values, + inputs_embeds=inputs_embeds, + use_cache=use_cache, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=True, + cache_position=cache_position, + **kwargs, + ) + + output = Qwen2_5_VLModelOutputWithPast( + last_hidden_state=outputs.last_hidden_state, + past_key_values=outputs.past_key_values, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + rope_deltas=self.rope_deltas, + ) + return output if return_dict else output.to_tuple() + + +@dataclass +@auto_docstring( + custom_intro=""" + Base class for Qwen2_5_VL causal language model (or autoregressive) outputs. + """ +) +class Qwen2_5_VLCausalLMOutputWithPast(ModelOutput): + r""" + loss (`torch.FloatTensor` of shape `(1,)`, *optional*, returned when `labels` is provided): + Language modeling loss (for next-token prediction). + logits (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.vocab_size)`): + Prediction scores of the language modeling head (scores for each vocabulary token before SoftMax). + past_key_values (`Cache`, *optional*, returned when `use_cache=True` is passed or when `config.use_cache=True`): + It is a [`~cache_utils.Cache`] instance. For more details, see our [kv cache guide](https://huggingface.co/docs/transformers/en/kv_cache). + + Contains pre-computed hidden-states (key and values in the self-attention blocks) that can be used (see + `past_key_values` input) to speed up sequential decoding. + rope_deltas (`torch.LongTensor` of shape `(batch_size, )`, *optional*): + The rope index difference between sequence length and multimodal rope. + """ + + loss: torch.FloatTensor | None = None + logits: torch.FloatTensor | None = None + past_key_values: Cache | None = None + hidden_states: tuple[torch.FloatTensor] | None = None + attentions: tuple[torch.FloatTensor] | None = None + rope_deltas: torch.LongTensor | None = None + + +class Qwen2_5_VLForConditionalGeneration(Qwen2_5_VLPreTrainedModel, GenerationMixin): + _checkpoint_conversion_mapping = { + "^visual": "model.visual", + r"^model(?!\.(language_model|visual))": "model.language_model", + } + _tied_weights_keys = {"lm_head.weight": "model.language_model.embed_tokens.weight"} + # Reference: fix gemma3 grad acc #37208 + accepts_loss_kwargs = False + + def __init__(self, config): + super().__init__(config) + self.model = Qwen2_5_VLModel(config) + self.lm_head = nn.Linear(config.text_config.hidden_size, config.text_config.vocab_size, bias=False) + + self.post_init() + + def get_input_embeddings(self): + return self.model.get_input_embeddings() + + def set_input_embeddings(self, value): + self.model.set_input_embeddings(value) + + @auto_docstring + def get_video_features( + self, + pixel_values_videos: torch.FloatTensor, + video_grid_thw: torch.LongTensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple | BaseModelOutputWithPooling: + r""" + pixel_values_videos (`torch.FloatTensor` of shape `(batch_size, num_channels, image_size, image_size)`): + The tensors corresponding to the input videos. + video_grid_thw (`torch.LongTensor` of shape `(num_videos, 3)`, *optional*): + The temporal, height and width of feature shape of each video in LLM. + """ + return self.model.get_video_features( + pixel_values_videos=pixel_values_videos, video_grid_thw=video_grid_thw, **kwargs + ) + + @auto_docstring + def get_image_features( + self, + pixel_values: torch.FloatTensor, + image_grid_thw: torch.LongTensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple | BaseModelOutputWithPooling: + r""" + pixel_values (`torch.FloatTensor` of shape `(batch_size, num_channels, image_size, image_size)`): + The tensors corresponding to the input images. + image_grid_thw (`torch.LongTensor` of shape `(num_images, 3)`, *optional*): + The temporal, height and width of feature shape of each image in LLM. + """ + return self.model.get_image_features(pixel_values=pixel_values, image_grid_thw=image_grid_thw, **kwargs) + + @can_return_tuple + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.Tensor | None = None, + position_ids: torch.LongTensor | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.FloatTensor | None = None, + labels: torch.LongTensor | None = None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + pixel_values: torch.Tensor | None = None, + pixel_values_videos: torch.FloatTensor | None = None, + image_grid_thw: torch.LongTensor | None = None, + video_grid_thw: torch.LongTensor | None = None, + rope_deltas: torch.LongTensor | None = None, + mm_token_type_ids: torch.IntTensor | None = None, + cache_position: torch.LongTensor | None = None, + second_per_grid_ts: torch.Tensor | None = None, + logits_to_keep: int | torch.Tensor = 0, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple | Qwen2_5_VLCausalLMOutputWithPast: + r""" + labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Labels for computing the masked language modeling loss. Indices should either be in `[0, ..., + config.vocab_size]` or -100 (see `input_ids` docstring). Tokens with indices set to `-100` are ignored + (masked), the loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]`. + image_grid_thw (`torch.LongTensor` of shape `(num_images, 3)`, *optional*): + The temporal, height and width of feature shape of each image in LLM. + video_grid_thw (`torch.LongTensor` of shape `(num_videos, 3)`, *optional*): + The temporal, height and width of feature shape of each video in LLM. + rope_deltas (`torch.LongTensor` of shape `(batch_size, )`, *optional*): + The rope index difference between sequence length and multimodal rope. + second_per_grid_ts (`torch.Tensor` of shape `(num_videos)`, *optional*): + The time interval (in seconds) for each grid along the temporal dimension in the 3D position IDs. + + Example: + + ```python + >>> from transformers import AutoProcessor, Qwen2_5_VLForConditionalGeneration + + >>> model = Qwen2_5_VLForConditionalGeneration.from_pretrained("Qwen/Qwen2.5-VL-7B-Instruct") + >>> processor = AutoProcessor.from_pretrained("Qwen/Qwen2.5-VL-7B-Instruct") + + >>> messages = [ + { + "role": "user", + "content": [ + { + "type": "image", + "image": "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg", + }, + {"type": "text", "text": "Describe the image."}, + ], + } + ] + + >>> inputs = processor.apply_chat_template( + messages, + tokenize=True, + add_generation_prompt=True, + return_dict=True, + return_tensors="pt" + ) + + >>> # Generate + >>> generated_ids = model.generate(**inputs, max_new_tokens=1024) + >>> generated_ids_trimmed = [out_ids[len(in_ids) :] for in_ids, out_ids in zip(inputs.input_ids, generated_ids)] + >>> output_text = processor.batch_decode(generated_ids_trimmed, skip_special_tokens=True, clean_up_tokenization_spaces=False)[0] + >>> print(output_text) + ``` + """ + + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + + outputs = self.model( + input_ids=input_ids, + pixel_values=pixel_values, + pixel_values_videos=pixel_values_videos, + image_grid_thw=image_grid_thw, + video_grid_thw=video_grid_thw, + second_per_grid_ts=second_per_grid_ts, + mm_token_type_ids=mm_token_type_ids, + position_ids=position_ids, + attention_mask=attention_mask, + past_key_values=past_key_values, + inputs_embeds=inputs_embeds, + use_cache=use_cache, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=True, + cache_position=cache_position, + **kwargs, + ) + + hidden_states = outputs[0] + + # Only compute necessary logits, and do not upcast them to float if we are not computing the loss + slice_indices = slice(-logits_to_keep, None) if isinstance(logits_to_keep, int) else logits_to_keep + logits = self.lm_head(hidden_states[:, slice_indices, :]) + + loss = None + if labels is not None: + loss = self.loss_function( + logits=logits, labels=labels, vocab_size=self.config.text_config.vocab_size, **kwargs + ) + + return Qwen2_5_VLCausalLMOutputWithPast( + loss=loss, + logits=logits, + past_key_values=outputs.past_key_values, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + rope_deltas=outputs.rope_deltas, + ) + + def prepare_inputs_for_generation( + self, + input_ids, + past_key_values=None, + attention_mask=None, + inputs_embeds=None, + cache_position=None, + position_ids=None, + use_cache=True, + pixel_values=None, + pixel_values_videos=None, + image_grid_thw=None, + video_grid_thw=None, + second_per_grid_ts=None, + is_first_iteration=False, + **kwargs, + ): + # Overwritten -- in specific circumstances we don't want to forward image inputs to the model + + model_inputs = super().prepare_inputs_for_generation( + input_ids, + past_key_values=past_key_values, + attention_mask=attention_mask, + inputs_embeds=inputs_embeds, + cache_position=cache_position, + position_ids=position_ids, + pixel_values=pixel_values, + pixel_values_videos=pixel_values_videos, + image_grid_thw=image_grid_thw, + video_grid_thw=video_grid_thw, + second_per_grid_ts=second_per_grid_ts, + use_cache=use_cache, + is_first_iteration=is_first_iteration, + **kwargs, + ) + + if not is_first_iteration and use_cache: + model_inputs["pixel_values"] = None + model_inputs["pixel_values_videos"] = None + + return model_inputs + + def _prepare_position_ids_for_generation(self, inputs_tensor, model_kwargs): + # Overwritten -- requires 3D position ids + + text_positions = super()._prepare_position_ids_for_generation(inputs_tensor, model_kwargs) + + # Early exit in case we are continuing generation from past kv + past_length = 0 + if (cache := model_kwargs.get("past_key_values")) is not None: + past_length = cache.get_seq_length() + if past_length != 0 and self.model.rope_deltas is not None: + position_ids = text_positions[None, ...] + self.model.rope_deltas + return position_ids + + # Otherwise compute 3d position ids for vision tokens and concat with text position ids + if "input_ids" in model_kwargs and model_kwargs["input_ids"].shape[1] > 0: + inputs_tensor = model_kwargs["input_ids"] + + is_input_ids = len(inputs_tensor.shape) == 2 and inputs_tensor.dtype in [torch.int, torch.long] + if ( + is_input_ids + and model_kwargs.get("mm_token_type_ids") is not None + and (model_kwargs.get("image_grid_thw") is not None or model_kwargs.get("video_grid_thw") is not None) + ): + model_kwargs = {k: v for k, v in model_kwargs.items() if k != "input_ids"} + vision_positions, rope_deltas = self.model.get_rope_index(inputs_tensor, **model_kwargs) + self.model.rope_deltas = rope_deltas + else: + vision_positions = text_positions.unsqueeze(0).expand(3, -1, -1) + self.model.rope_deltas = torch.zeros( + inputs_tensor.shape[0], 1, dtype=torch.long, device=inputs_tensor.device + ) + + # Concatenate "text + vision" positions into [4, bs, seq-len] + text_positions = text_positions[None, ...] + position_ids = torch.cat([text_positions, vision_positions], dim=0) + + return position_ids + + def _get_image_nums_and_video_nums( + self, + input_ids: torch.LongTensor | None, + inputs_embeds: torch.Tensor | None = None, + ) -> tuple[torch.Tensor, torch.Tensor]: + """ + Get the number of images and videos for each sample to calculate the separation length of the sample tensor. + These parameters are not passed through the processor to avoid unpredictable impacts from interface modifications. + + Args: + input_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`): + Indices of input sequence tokens in the vocabulary. + + Returns: + image_nums (`torch.LongTensor` of shape `(batch_size, num_images_sample)`) + video_nums (`torch.LongTensor` of shape `(batch_size, num_videos_sample)`) + """ + image_token_id = self.config.image_token_id + video_token_id = self.config.video_token_id + vision_start_token_id = self.config.vision_start_token_id + + if inputs_embeds is not None: + vision_start_mask = ( + inputs_embeds + == self.get_input_embeddings()( + torch.tensor(vision_start_token_id, dtype=torch.long, device=inputs_embeds.device) + ) + )[..., 0] + image_mask = ( + inputs_embeds + == self.get_input_embeddings()( + torch.tensor(image_token_id, dtype=torch.long, device=inputs_embeds.device) + ) + )[..., 0] + video_mask = ( + inputs_embeds + == self.get_input_embeddings()( + torch.tensor(video_token_id, dtype=torch.long, device=inputs_embeds.device) + ) + )[..., 0] + else: + vision_start_mask = input_ids == vision_start_token_id + image_mask = input_ids == image_token_id + video_mask = input_ids == video_token_id + + vision_first_mask = torch.roll(vision_start_mask, shifts=1, dims=1) + image_nums = torch.sum(vision_first_mask & image_mask, dim=1) + video_nums = torch.sum(vision_first_mask & video_mask, dim=1) + + return image_nums, video_nums + + def _expand_inputs_for_generation( + self, + expand_size: int = 1, + is_encoder_decoder: bool = False, + input_ids: torch.LongTensor | None = None, + **model_kwargs, + ) -> tuple[torch.LongTensor, dict[str, Any]]: + # Overwritten -- Support for expanding tensors without a batch size dimension + # e.g., pixel_values, image_grid_thw, pixel_values_videos, video_grid_thw, second_per_grid_t + # pixel_values.shape[0] is sum(seqlen_images for samples) + # image_grid_thw.shape[0] is sum(num_images for samples) + + if expand_size == 1: + return input_ids, model_kwargs + + visual_keys = ["pixel_values", "image_grid_thw", "pixel_values_videos", "video_grid_thw", "second_per_grid_ts"] + + def _expand_dict_for_generation_visual(dict_to_expand): + image_grid_thw = model_kwargs.get("image_grid_thw", None) + video_grid_thw = model_kwargs.get("video_grid_thw", None) + image_nums, video_nums = self._get_image_nums_and_video_nums( + input_ids, inputs_embeds=model_kwargs.get("inputs_embeds", None) + ) + + def _repeat_interleave_samples(x, lengths, repeat_times): + samples = torch.split(x, lengths) + repeat_args = [repeat_times] + [1] * (x.dim() - 1) + result = torch.cat([sample.repeat(*repeat_args) for sample in samples], dim=0) + return result + + for key in dict_to_expand: + if key == "pixel_values": + # split images into samples + samples = torch.split(image_grid_thw, list(image_nums)) + # compute the sequence length of images for each sample + lengths = [torch.prod(sample, dim=1).sum() for sample in samples] + dict_to_expand[key] = _repeat_interleave_samples( + dict_to_expand[key], lengths=lengths, repeat_times=expand_size + ) + elif key == "image_grid_thw": + # get the num of images for each sample + lengths = list(image_nums) + dict_to_expand[key] = _repeat_interleave_samples( + dict_to_expand[key], lengths=lengths, repeat_times=expand_size + ) + elif key == "pixel_values_videos": + samples = torch.split(video_grid_thw, list(video_nums)) + lengths = [torch.prod(sample, dim=1).sum() for sample in samples] + dict_to_expand[key] = _repeat_interleave_samples( + dict_to_expand[key], lengths=lengths, repeat_times=expand_size + ) + elif key == "video_grid_thw": + lengths = list(video_nums) + dict_to_expand[key] = _repeat_interleave_samples( + dict_to_expand[key], lengths=lengths, repeat_times=expand_size + ) + elif key == "second_per_grid_ts": + dict_to_expand[key] = _repeat_interleave_samples( + dict_to_expand[key], lengths=list(video_nums), repeat_times=expand_size + ) + return dict_to_expand + + def _expand_dict_for_generation(dict_to_expand): + for key in dict_to_expand: + if key == "position_ids" and dict_to_expand[key].ndim == 3: + dict_to_expand[key] = dict_to_expand[key].repeat_interleave(expand_size, dim=1) + elif ( + key != "cache_position" + and dict_to_expand[key] is not None + and isinstance(dict_to_expand[key], torch.Tensor) + and key not in visual_keys + ): + dict_to_expand[key] = dict_to_expand[key].repeat_interleave(expand_size, dim=0) + return dict_to_expand + + model_kwargs = _expand_dict_for_generation_visual(model_kwargs) + + if input_ids is not None: + input_ids = input_ids.repeat_interleave(expand_size, dim=0) + + model_kwargs = _expand_dict_for_generation(model_kwargs) + + if is_encoder_decoder: + if model_kwargs.get("encoder_outputs") is None: + raise ValueError("If `is_encoder_decoder` is True, make sure that `encoder_outputs` is defined.") + model_kwargs["encoder_outputs"] = _expand_dict_for_generation(model_kwargs["encoder_outputs"]) + + return input_ids, model_kwargs + + +__all__ = ["Qwen2_5_VLForConditionalGeneration", "Qwen2_5_VLModel", "Qwen2_5_VLPreTrainedModel", "Qwen2_5_VLTextModel"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/qwen2_5_vl/modular_qwen2_5_vl.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/qwen2_5_vl/modular_qwen2_5_vl.py new file mode 100644 index 0000000000000000000000000000000000000000..093b4f2b783a0bc00fde4167a1d7649dfb7969b6 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/qwen2_5_vl/modular_qwen2_5_vl.py @@ -0,0 +1,955 @@ +# Copyright 2025 The Qwen Team and The HuggingFace Inc. team. All rights reserved. +# +# This code is based on EleutherAI's GPT-NeoX library and the GPT-NeoX +# and OPT implementations in this library. It has been modified from its +# original forms to accommodate minor architectural differences compared +# to GPT-NeoX and OPT used by the Meta AI team that trained the model. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""PyTorch Qwen2.5-VL model.""" + +import itertools + +import numpy as np +import torch +import torch.nn as nn +import torch.nn.functional as F + +from ... import initialization as init +from ...activations import ACT2FN +from ...cache_utils import Cache +from ...configuration_utils import PreTrainedConfig +from ...feature_extraction_utils import BatchFeature +from ...image_utils import ImageInput +from ...modeling_layers import GradientCheckpointingLayer +from ...modeling_outputs import BaseModelOutputWithPooling +from ...modeling_utils import PreTrainedModel +from ...processing_utils import MultiModalData, ProcessingKwargs, Unpack +from ...tokenization_utils_base import PreTokenizedInput, TextInput +from ...utils import logging +from ...utils.generic import merge_with_config_defaults +from ...utils.output_capturing import capture_outputs +from ...video_utils import VideoInput +from ..llama.modeling_llama import LlamaRMSNorm +from ..qwen2_vl.configuration_qwen2_vl import Qwen2VLConfig, Qwen2VLTextConfig +from ..qwen2_vl.modeling_qwen2_vl import ( + PatchEmbed, + PatchMerger, + Qwen2VLCausalLMOutputWithPast, + Qwen2VLForConditionalGeneration, + Qwen2VLModel, + Qwen2VLModelOutputWithPast, + Qwen2VLPreTrainedModel, + TransformersKwargs, + VisionAttention, + VisionRotaryEmbedding, +) +from ..qwen2_vl.processing_qwen2_vl import Qwen2VLProcessor + + +logger = logging.get_logger(__name__) + + +class Qwen2_5_VLVisionConfig(PreTrainedConfig): + model_type = "qwen2_5_vl" + base_config_key = "vision_config" + + def __init__( + self, + depth=32, + hidden_size=3584, + hidden_act="silu", + intermediate_size=3420, + num_heads=16, + in_channels=3, + patch_size=14, + spatial_merge_size=2, + temporal_patch_size=2, + tokens_per_second=4, + window_size=112, + out_hidden_size=3584, + fullatt_block_indexes=[7, 15, 23, 31], + initializer_range=0.02, + **kwargs, + ): + super().__init__(**kwargs) + + self.depth = depth + self.hidden_size = hidden_size + self.hidden_act = hidden_act + self.intermediate_size = intermediate_size + self.num_heads = num_heads + self.in_channels = in_channels + self.patch_size = patch_size + self.spatial_merge_size = spatial_merge_size + self.temporal_patch_size = temporal_patch_size + self.tokens_per_second = tokens_per_second + self.window_size = window_size + self.fullatt_block_indexes = fullatt_block_indexes + self.out_hidden_size = out_hidden_size + self.initializer_range = initializer_range + + +class Qwen2_5_VLTextConfig(Qwen2VLTextConfig): + model_type = "qwen2_5_vl_text" + + +class Qwen2_5_VLConfig(Qwen2VLConfig): + model_type = "qwen2_5_vl" + sub_configs = {"vision_config": Qwen2_5_VLVisionConfig, "text_config": Qwen2_5_VLTextConfig} + + +class Qwen2_5_VLRMSNorm(LlamaRMSNorm): + pass + + +class Qwen2_5_VLMLP(nn.Module): + def __init__(self, config, bias: bool = False): + super().__init__() + self.hidden_size = config.hidden_size + self.intermediate_size = config.intermediate_size + self.gate_proj = nn.Linear(self.hidden_size, self.intermediate_size, bias=bias) + self.up_proj = nn.Linear(self.hidden_size, self.intermediate_size, bias=bias) + self.down_proj = nn.Linear(self.intermediate_size, self.hidden_size, bias=bias) + self.act_fn = ACT2FN[config.hidden_act] + + def forward(self, hidden_state): + return self.down_proj(self.act_fn(self.gate_proj(hidden_state)) * self.up_proj(hidden_state)) + + +class Qwen2_5_VisionPatchEmbed(PatchEmbed): + pass + + +class Qwen2_5_VisionRotaryEmbedding(VisionRotaryEmbedding): + pass + + +class Qwen2_5_VLPatchMerger(PatchMerger): + def __init__(self, dim: int, context_dim: int, spatial_merge_size: int = 2) -> None: + super().__init__(dim, context_dim, spatial_merge_size) + self.ln_q = Qwen2_5_VLRMSNorm(context_dim, eps=1e-6) + + +class Qwen2_5_VLVisionAttention(VisionAttention): + def __init__(self, config: Qwen2_5_VLVisionConfig) -> None: + super().__init__(config) + self.dim = config.hidden_size + + +class Qwen2_5_VLVisionBlock(GradientCheckpointingLayer): + def __init__(self, config, attn_implementation: str = "sdpa") -> None: + super().__init__() + self.norm1 = Qwen2_5_VLRMSNorm(config.hidden_size, eps=1e-6) + self.norm2 = Qwen2_5_VLRMSNorm(config.hidden_size, eps=1e-6) + self.attn = Qwen2_5_VLVisionAttention(config=config) + self.mlp = Qwen2_5_VLMLP(config, bias=True) + + def forward( + self, + hidden_states: torch.Tensor, + cu_seqlens: torch.Tensor, + rotary_pos_emb: torch.Tensor | None = None, + position_embeddings: tuple[torch.Tensor, torch.Tensor] | None = None, + **kwargs, + ) -> torch.Tensor: + hidden_states = hidden_states + self.attn( + self.norm1(hidden_states), + cu_seqlens=cu_seqlens, + rotary_pos_emb=rotary_pos_emb, + position_embeddings=position_embeddings, + **kwargs, + ) + hidden_states = hidden_states + self.mlp(self.norm2(hidden_states)) + return hidden_states + + +class Qwen2_5_VLPreTrainedModel(Qwen2VLPreTrainedModel): + def _init_weights(self, module): + PreTrainedModel._init_weights(self, module) + if isinstance(module, Qwen2_5_VisionRotaryEmbedding): + inv_freq = 1.0 / (module.theta ** (torch.arange(0, module.dim, 2, dtype=torch.float) / module.dim)) + init.copy_(module.inv_freq, inv_freq) + + +class Qwen2_5_VisionTransformerPretrainedModel(Qwen2_5_VLPreTrainedModel): + config: Qwen2_5_VLVisionConfig + _no_split_modules = ["Qwen2_5_VLVisionBlock"] + _input_embed_layer = "patch_embed" + _can_record_outputs = { + "hidden_states": Qwen2_5_VLVisionBlock, + "attentions": Qwen2_5_VLVisionAttention, + } + + def __init__(self, config, *inputs, **kwargs) -> None: + super().__init__(config, *inputs, **kwargs) + self.spatial_merge_size = config.spatial_merge_size + self.patch_size = config.patch_size + self.fullatt_block_indexes = config.fullatt_block_indexes + self.window_size = config.window_size + self.spatial_merge_unit = self.spatial_merge_size * self.spatial_merge_size + + self.patch_embed = Qwen2_5_VisionPatchEmbed( + patch_size=config.patch_size, + temporal_patch_size=config.temporal_patch_size, + in_channels=config.in_channels, + embed_dim=config.hidden_size, + ) + + head_dim = config.hidden_size // config.num_heads + self.rotary_pos_emb = Qwen2_5_VisionRotaryEmbedding(head_dim // 2) + + self.blocks = nn.ModuleList([Qwen2_5_VLVisionBlock(config) for _ in range(config.depth)]) + self.merger = Qwen2_5_VLPatchMerger( + dim=config.out_hidden_size, + context_dim=config.hidden_size, + spatial_merge_size=config.spatial_merge_size, + ) + self.gradient_checkpointing = False + + self.post_init() + + def rot_pos_emb(self, grid_thw): + pos_ids = [] + for t, h, w in grid_thw.tolist(): + hpos_ids = torch.arange(h).unsqueeze(1).expand(-1, w) + hpos_ids = hpos_ids.reshape( + h // self.spatial_merge_size, + self.spatial_merge_size, + w // self.spatial_merge_size, + self.spatial_merge_size, + ) + hpos_ids = hpos_ids.permute(0, 2, 1, 3) + hpos_ids = hpos_ids.flatten() + + wpos_ids = torch.arange(w).unsqueeze(0).expand(h, -1) + wpos_ids = wpos_ids.reshape( + h // self.spatial_merge_size, + self.spatial_merge_size, + w // self.spatial_merge_size, + self.spatial_merge_size, + ) + wpos_ids = wpos_ids.permute(0, 2, 1, 3) + wpos_ids = wpos_ids.flatten() + pos_ids.append(torch.stack([hpos_ids, wpos_ids], dim=-1).repeat(t, 1)) + pos_ids = torch.cat(pos_ids, dim=0) + max_grid_size = grid_thw[:, 1:].max() + rotary_pos_emb_full = self.rotary_pos_emb(max_grid_size) + rotary_pos_emb = rotary_pos_emb_full[pos_ids].flatten(1) + return rotary_pos_emb + + def get_window_index(self, grid_thw): + window_index: list = [] + cu_window_seqlens: list = [0] + window_index_id = 0 + vit_merger_window_size = self.window_size // self.spatial_merge_size // self.patch_size + grid_thw_list = grid_thw.tolist() + + for grid_t, grid_h, grid_w in grid_thw_list: + llm_grid_h, llm_grid_w = ( + grid_h // self.spatial_merge_size, + grid_w // self.spatial_merge_size, + ) + index = torch.arange(grid_t * llm_grid_h * llm_grid_w).reshape(grid_t, llm_grid_h, llm_grid_w) + pad_h = vit_merger_window_size - llm_grid_h % vit_merger_window_size + pad_w = vit_merger_window_size - llm_grid_w % vit_merger_window_size + num_windows_h = (llm_grid_h + pad_h) // vit_merger_window_size + num_windows_w = (llm_grid_w + pad_w) // vit_merger_window_size + index_padded = F.pad(index, (0, pad_w, 0, pad_h), "constant", -100) + index_padded = index_padded.reshape( + grid_t, + num_windows_h, + vit_merger_window_size, + num_windows_w, + vit_merger_window_size, + ) + index_padded = index_padded.permute(0, 1, 3, 2, 4).reshape( + grid_t, + num_windows_h * num_windows_w, + vit_merger_window_size, + vit_merger_window_size, + ) + seqlens = (index_padded != -100).sum([2, 3]).reshape(-1) + index_padded = index_padded.reshape(-1) + index_new = index_padded[index_padded != -100] + window_index.append(index_new + window_index_id) + cu_seqlens_tmp = seqlens.cumsum(0) * self.spatial_merge_unit + cu_window_seqlens[-1] + cu_window_seqlens.extend(cu_seqlens_tmp.tolist()) + window_index_id += grid_t * llm_grid_h * llm_grid_w + window_index = torch.cat(window_index, dim=0) + + return window_index, cu_window_seqlens + + @merge_with_config_defaults + @capture_outputs + def forward( + self, hidden_states: torch.Tensor, grid_thw: torch.Tensor, **kwargs: Unpack[TransformersKwargs] + ) -> tuple | BaseModelOutputWithPooling: + """ + Args: + hidden_states (`torch.Tensor` of shape `(seq_len, hidden_size)`): + The final hidden states of the model. + grid_thw (`torch.Tensor` of shape `(num_images_or_videos, 3)`): + The temporal, height and width of feature shape of each image in LLM. + + Returns: + `torch.Tensor`: hidden_states. + """ + hidden_states = self.patch_embed(hidden_states) + rotary_pos_emb = self.rot_pos_emb(grid_thw) + window_index, cu_window_seqlens = self.get_window_index(grid_thw) + cu_window_seqlens = torch.tensor( + cu_window_seqlens, + device=hidden_states.device, + dtype=grid_thw.dtype if torch.jit.is_tracing() else torch.int32, + ) + cu_window_seqlens = torch.unique_consecutive(cu_window_seqlens) + + seq_len, _ = hidden_states.size() + hidden_states = hidden_states.reshape(seq_len // self.spatial_merge_unit, self.spatial_merge_unit, -1) + hidden_states = hidden_states[window_index, :, :] + hidden_states = hidden_states.reshape(seq_len, -1) + rotary_pos_emb = rotary_pos_emb.reshape(seq_len // self.spatial_merge_unit, self.spatial_merge_unit, -1) + rotary_pos_emb = rotary_pos_emb[window_index, :, :] + rotary_pos_emb = rotary_pos_emb.reshape(seq_len, -1) + emb = torch.cat((rotary_pos_emb, rotary_pos_emb), dim=-1) + position_embeddings = (emb.cos(), emb.sin()) + + cu_seqlens = torch.repeat_interleave(grid_thw[:, 1] * grid_thw[:, 2], grid_thw[:, 0]).cumsum( + dim=0, + # Select dtype based on the following factors: + # - FA2 requires that cu_seqlens_q must have dtype int32 + # - torch.onnx.export requires that cu_seqlens_q must have same dtype as grid_thw + # See https://github.com/huggingface/transformers/pull/34852 for more information + dtype=grid_thw.dtype if torch.jit.is_tracing() else torch.int32, + ) + cu_seqlens = F.pad(cu_seqlens, (1, 0), value=0) + + for layer_num, blk in enumerate(self.blocks): + if layer_num in self.fullatt_block_indexes: + cu_seqlens_now = cu_seqlens + else: + cu_seqlens_now = cu_window_seqlens + + hidden_states = blk( + hidden_states, + cu_seqlens=cu_seqlens_now, + position_embeddings=position_embeddings, + **kwargs, + ) + + merged_hidden_states = self.merger(hidden_states) + reverse_indices = torch.argsort(window_index) + merged_hidden_states = merged_hidden_states[reverse_indices, :] + + return BaseModelOutputWithPooling( + last_hidden_state=hidden_states, + pooler_output=merged_hidden_states, + ) + + +class Qwen2_5_VLModelOutputWithPast(Qwen2VLModelOutputWithPast): + pass + + +class Qwen2_5_VLModel(Qwen2VLModel): + config: Qwen2_5_VLConfig + base_model_prefix = "model" + _no_split_modules = ["Qwen2_5_VLDecoderLayer", "Qwen2_5_VLVisionBlock"] + # Reference: fix gemma3 grad acc #37208 + accepts_loss_kwargs = False + + def __init__(self, config): + super().__init__(config) + self.visual = Qwen2_5_VisionTransformerPretrainedModel._from_config(config.vision_config) + + def get_rope_index( + self, + input_ids: torch.LongTensor, + mm_token_type_ids: torch.IntTensor, + image_grid_thw: torch.LongTensor | None = None, + video_grid_thw: torch.LongTensor | None = None, + second_per_grid_ts: torch.Tensor | None = None, + attention_mask: torch.Tensor | None = None, + **kwargs, + ) -> tuple[torch.Tensor, torch.Tensor]: + """ + Calculate the 3D rope index based on image and video's sizes. The utility expects a `vision + text` + sequence and will error out otherwise. For pure text sequence, please rely on model's auto-inferred + position ids. In a mixed vision + text sequence, vision tokens use 3D RoPE (temporal, height, width) + while text tokens use standard 1D RoPE. + + Example: + Temporal patches: 3; Height patches: 2; Width patches: 2 + Each vision input results in (temporal x height × width) positions. Here: 3 x 2 × 2 = 12 positions total. + + Temporal position IDs are spaced by: + `interval = tokens_per_second * temporal_patch_size / fps` + + If fps = 1; tokens_per_second = 25; temporal_patch_size = 2, temporal IDs increase by 50 for each temporal patch: + `[0, 0, 0, 0, 50, 50, 50, 50, 100, 100, 100, 100]` + + Height IDs repeat per row: `[0, 0, 1, 1, ...]` + Width IDs alternate per column: `[0, 1, 0, 1, ...]` + Text tokens follow standard 1D RoPE and the position IDs grow consequently with a step of `1` + + Args: + input_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`): + Indices of input sequence tokens in the vocabulary. Padding will be ignored by default should you provide + it. + mm_token_type_ids (`torch.IntTensor` of shape `(batch_size, sequence_length)`): + Token type ids matching each modality to a different value in the input sequence, i.e. text (0), image (1), video (2). + image_grid_thw (`torch.LongTensor` of shape `(num_images, 3)`, *optional*): + The temporal, height and width of feature shape of each image in LLM. + video_grid_thw (`torch.LongTensor` of shape `(num_videos, 3)`, *optional*): + The temporal, height and width of feature shape of each video in LLM. + second_per_grid_ts (`torch.Tensor` of shape `(num_videos)`, *optional*): + The time interval (in seconds) for each grid along the temporal dimension in the 3D position IDs. + attention_mask (`torch.Tensor` of shape `(batch_size, sequence_length)`, *optional*): + Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`: + + - 1 for tokens that are **not masked**, + - 0 for tokens that are **masked**. + + Returns: + position_ids (`torch.LongTensor` of shape `(3, batch_size, sequence_length)`) + mrope_position_deltas (`torch.Tensor` of shape `(batch_size)`) + """ + spatial_merge_size = self.config.vision_config.spatial_merge_size + tokens_per_second = self.config.vision_config.tokens_per_second + + mrope_position_deltas = [] + position_ids = torch.zeros( + 3, + input_ids.shape[0], + input_ids.shape[1], + dtype=input_ids.dtype, + device=input_ids.device, + ) + grid_iters = { + 1: iter(image_grid_thw) if image_grid_thw is not None else None, + 2: iter(video_grid_thw) if video_grid_thw is not None else None, + } + second_per_grid_ts = ( + iter(second_per_grid_ts) if second_per_grid_ts is not None else iter([1] * input_ids.shape[1]) + ) + for batch_idx, current_input_ids in enumerate(input_ids): + input_token_type = mm_token_type_ids[batch_idx] + if attention_mask is not None: + current_input_ids = current_input_ids[attention_mask[batch_idx].bool()] + input_token_type = input_token_type[attention_mask[batch_idx].bool()] + + input_type_group = [] + for key, group in itertools.groupby(enumerate(input_token_type.tolist()), lambda x: x[1]): + group = list(group) + start_index = group[0][0] + end_index = group[-1][0] + 1 + input_type_group.append((key, start_index, end_index)) + + current_pos = 0 + llm_pos_ids_list = [] + for modality_type, start_idx, end_idx in input_type_group: + # text == 0 + if modality_type == 0: + text_len = end_idx - start_idx + llm_pos_ids_list.append( + torch.arange(text_len, device=input_ids.device).view(1, -1).expand(3, -1) + current_pos + ) + current_pos += text_len + # image == 1, video == 2 + else: + grid_thw = next(grid_iters[modality_type]) + time_interval = tokens_per_second * int(next(second_per_grid_ts)) + vision_position_ids = self.get_vision_position_ids( + current_pos, grid_thw, 1, spatial_merge_size, time_interval, device=input_ids.device + ) + llm_pos_ids_list.append(vision_position_ids) + current_pos += max(grid_thw[1], grid_thw[2]) // spatial_merge_size + llm_positions = torch.cat(llm_pos_ids_list, dim=1).reshape(3, -1) + if attention_mask is not None: + position_ids[:, batch_idx, attention_mask[batch_idx].bool()] = llm_positions.to(position_ids.device) + else: + position_ids[:, batch_idx] = llm_positions.to(position_ids.device) + mrope_position_deltas.append(llm_positions.max() + 1 - len(current_input_ids)) + mrope_position_deltas = torch.tensor(mrope_position_deltas, device=input_ids.device).unsqueeze(1) + return position_ids, mrope_position_deltas + + def compute_3d_position_ids( + self, + input_ids: torch.Tensor | None, + image_grid_thw: torch.Tensor | None, + video_grid_thw: torch.Tensor | None, + inputs_embeds: torch.Tensor | None, + attention_mask: torch.Tensor | None, + past_key_values: torch.Tensor | None, + second_per_grid_ts: torch.Tensor | None = None, + mm_token_type_ids: torch.IntTensor | None = None, + ) -> torch.Tensor | None: + past_key_values_length = 0 if past_key_values is None else past_key_values.get_seq_length() + can_compute_mrope = ( + input_ids is not None + and mm_token_type_ids is not None + and (image_grid_thw is not None or video_grid_thw is not None) + ) + + if can_compute_mrope and (self.rope_deltas is None or past_key_values_length == 0): + position_ids, rope_deltas = self.get_rope_index( + input_ids, + image_grid_thw=image_grid_thw, + video_grid_thw=video_grid_thw, + attention_mask=attention_mask, + second_per_grid_ts=second_per_grid_ts, + mm_token_type_ids=mm_token_type_ids, + ) + self.rope_deltas = rope_deltas + # Use pre-calculated rope-deltas to infer correct 3D position ids + elif self.rope_deltas is not None: + batch_size, seq_length, _ = inputs_embeds.shape + if attention_mask is not None: + position_ids = attention_mask.long().cumsum(-1) - 1 + position_ids = position_ids.masked_fill(attention_mask == 0, 0) + position_ids = position_ids.view(1, batch_size, -1).repeat(3, 1, 1).to(inputs_embeds.device) + else: + position_ids = torch.arange(past_key_values_length, past_key_values_length + seq_length) + position_ids = position_ids.view(1, 1, -1).expand(3, batch_size, -1).to(inputs_embeds.device) + delta = self.rope_deltas.repeat_interleave(batch_size // self.rope_deltas.shape[0], dim=0) + position_ids = position_ids + delta.to(device=position_ids.device) + else: + # Can't build correct 3D positions. Let the model infer it from `cache_position` + position_ids = None + return position_ids + + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.Tensor | None = None, + position_ids: torch.LongTensor | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.FloatTensor | None = None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + pixel_values: torch.Tensor | None = None, + pixel_values_videos: torch.FloatTensor | None = None, + image_grid_thw: torch.LongTensor | None = None, + video_grid_thw: torch.LongTensor | None = None, + rope_deltas: torch.LongTensor | None = None, + mm_token_type_ids: torch.IntTensor | None = None, + cache_position: torch.LongTensor | None = None, + second_per_grid_ts: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple | Qwen2_5_VLModelOutputWithPast: + r""" + image_grid_thw (`torch.LongTensor` of shape `(num_images, 3)`, *optional*): + The temporal, height and width of feature shape of each image in LLM. + video_grid_thw (`torch.LongTensor` of shape `(num_videos, 3)`, *optional*): + The temporal, height and width of feature shape of each video in LLM. + rope_deltas (`torch.LongTensor` of shape `(batch_size, )`, *optional*): + The rope index difference between sequence length and multimodal rope. + second_per_grid_ts (`torch.Tensor` of shape `(num_videos)`, *optional*): + The time interval (in seconds) for each grid along the temporal dimension in the 3D position IDs. + """ + + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + if inputs_embeds is None: + inputs_embeds = self.get_input_embeddings()(input_ids) + + if pixel_values is not None: + image_embeds = self.get_image_features(pixel_values, image_grid_thw, return_dict=True).pooler_output + image_embeds = torch.cat(image_embeds, dim=0).to(inputs_embeds.device, inputs_embeds.dtype) + image_mask, _ = self.get_placeholder_mask( + input_ids, inputs_embeds=inputs_embeds, image_features=image_embeds + ) + inputs_embeds = inputs_embeds.masked_scatter(image_mask, image_embeds) + + if pixel_values_videos is not None: + video_embeds = self.get_video_features(pixel_values_videos, video_grid_thw, return_dict=True).pooler_output + video_embeds = torch.cat(video_embeds, dim=0).to(inputs_embeds.device, inputs_embeds.dtype) + _, video_mask = self.get_placeholder_mask( + input_ids, inputs_embeds=inputs_embeds, video_features=video_embeds + ) + inputs_embeds = inputs_embeds.masked_scatter(video_mask, video_embeds) + + if position_ids is None: + position_ids = self.compute_3d_position_ids( + input_ids=input_ids, + image_grid_thw=image_grid_thw, + video_grid_thw=video_grid_thw, + second_per_grid_ts=second_per_grid_ts, + inputs_embeds=inputs_embeds, + attention_mask=attention_mask, + past_key_values=past_key_values, + mm_token_type_ids=mm_token_type_ids, + ) + + outputs = self.language_model( + input_ids=None, + position_ids=position_ids, + attention_mask=attention_mask, + past_key_values=past_key_values, + inputs_embeds=inputs_embeds, + use_cache=use_cache, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=True, + cache_position=cache_position, + **kwargs, + ) + + output = Qwen2_5_VLModelOutputWithPast( + last_hidden_state=outputs.last_hidden_state, + past_key_values=outputs.past_key_values, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + rope_deltas=self.rope_deltas, + ) + return output if return_dict else output.to_tuple() + + +class Qwen2_5_VLCausalLMOutputWithPast(Qwen2VLCausalLMOutputWithPast): + pass + + +class Qwen2_5_VLForConditionalGeneration(Qwen2VLForConditionalGeneration): + # Reference: fix gemma3 grad acc #37208 + accepts_loss_kwargs = False + + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.Tensor | None = None, + position_ids: torch.LongTensor | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.FloatTensor | None = None, + labels: torch.LongTensor | None = None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + pixel_values: torch.Tensor | None = None, + pixel_values_videos: torch.FloatTensor | None = None, + image_grid_thw: torch.LongTensor | None = None, + video_grid_thw: torch.LongTensor | None = None, + rope_deltas: torch.LongTensor | None = None, + mm_token_type_ids: torch.IntTensor | None = None, + cache_position: torch.LongTensor | None = None, + second_per_grid_ts: torch.Tensor | None = None, + logits_to_keep: int | torch.Tensor = 0, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple | Qwen2_5_VLCausalLMOutputWithPast: + r""" + labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Labels for computing the masked language modeling loss. Indices should either be in `[0, ..., + config.vocab_size]` or -100 (see `input_ids` docstring). Tokens with indices set to `-100` are ignored + (masked), the loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]`. + image_grid_thw (`torch.LongTensor` of shape `(num_images, 3)`, *optional*): + The temporal, height and width of feature shape of each image in LLM. + video_grid_thw (`torch.LongTensor` of shape `(num_videos, 3)`, *optional*): + The temporal, height and width of feature shape of each video in LLM. + rope_deltas (`torch.LongTensor` of shape `(batch_size, )`, *optional*): + The rope index difference between sequence length and multimodal rope. + second_per_grid_ts (`torch.Tensor` of shape `(num_videos)`, *optional*): + The time interval (in seconds) for each grid along the temporal dimension in the 3D position IDs. + + Example: + + ```python + >>> from transformers import AutoProcessor, Qwen2_5_VLForConditionalGeneration + + >>> model = Qwen2_5_VLForConditionalGeneration.from_pretrained("Qwen/Qwen2.5-VL-7B-Instruct") + >>> processor = AutoProcessor.from_pretrained("Qwen/Qwen2.5-VL-7B-Instruct") + + >>> messages = [ + { + "role": "user", + "content": [ + { + "type": "image", + "image": "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg", + }, + {"type": "text", "text": "Describe the image."}, + ], + } + ] + + >>> inputs = processor.apply_chat_template( + messages, + tokenize=True, + add_generation_prompt=True, + return_dict=True, + return_tensors="pt" + ) + + >>> # Generate + >>> generated_ids = model.generate(**inputs, max_new_tokens=1024) + >>> generated_ids_trimmed = [out_ids[len(in_ids) :] for in_ids, out_ids in zip(inputs.input_ids, generated_ids)] + >>> output_text = processor.batch_decode(generated_ids_trimmed, skip_special_tokens=True, clean_up_tokenization_spaces=False)[0] + >>> print(output_text) + ``` + """ + + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + + outputs = self.model( + input_ids=input_ids, + pixel_values=pixel_values, + pixel_values_videos=pixel_values_videos, + image_grid_thw=image_grid_thw, + video_grid_thw=video_grid_thw, + second_per_grid_ts=second_per_grid_ts, + mm_token_type_ids=mm_token_type_ids, + position_ids=position_ids, + attention_mask=attention_mask, + past_key_values=past_key_values, + inputs_embeds=inputs_embeds, + use_cache=use_cache, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=True, + cache_position=cache_position, + **kwargs, + ) + + hidden_states = outputs[0] + + # Only compute necessary logits, and do not upcast them to float if we are not computing the loss + slice_indices = slice(-logits_to_keep, None) if isinstance(logits_to_keep, int) else logits_to_keep + logits = self.lm_head(hidden_states[:, slice_indices, :]) + + loss = None + if labels is not None: + loss = self.loss_function( + logits=logits, labels=labels, vocab_size=self.config.text_config.vocab_size, **kwargs + ) + + return Qwen2_5_VLCausalLMOutputWithPast( + loss=loss, + logits=logits, + past_key_values=outputs.past_key_values, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + rope_deltas=outputs.rope_deltas, + ) + + def prepare_inputs_for_generation( + self, + input_ids, + past_key_values=None, + attention_mask=None, + inputs_embeds=None, + cache_position=None, + position_ids=None, + use_cache=True, + pixel_values=None, + pixel_values_videos=None, + image_grid_thw=None, + video_grid_thw=None, + second_per_grid_ts=None, + is_first_iteration=False, + **kwargs, + ): + # Overwritten -- in specific circumstances we don't want to forward image inputs to the model + + model_inputs = super().prepare_inputs_for_generation( + input_ids, + past_key_values=past_key_values, + attention_mask=attention_mask, + inputs_embeds=inputs_embeds, + cache_position=cache_position, + position_ids=position_ids, + pixel_values=pixel_values, + pixel_values_videos=pixel_values_videos, + image_grid_thw=image_grid_thw, + video_grid_thw=video_grid_thw, + second_per_grid_ts=second_per_grid_ts, + use_cache=use_cache, + is_first_iteration=is_first_iteration, + **kwargs, + ) + + if not is_first_iteration and use_cache: + model_inputs["pixel_values"] = None + model_inputs["pixel_values_videos"] = None + + return model_inputs + + +class Qwen2_5_VLProcessorKwargs(ProcessingKwargs, total=False): + _defaults = { + "text_kwargs": { + "padding": False, + "return_mm_token_type_ids": True, + }, + "videos_kwargs": {"return_metadata": True}, + } + + +class Qwen2_5_VLProcessor(Qwen2VLProcessor): + @property + def model_input_names(self): + tokenizer_input_names = self.tokenizer.model_input_names + image_processor_input_names = self.image_processor.model_input_names + video_processor_input_names = self.video_processor.model_input_names + names_from_processor = list( + dict.fromkeys(tokenizer_input_names + image_processor_input_names + video_processor_input_names) + ) + return names_from_processor + ["second_per_grid_ts", "mm_token_type_ids"] + + def __call__( + self, + images: ImageInput | None = None, + text: TextInput | PreTokenizedInput | list[TextInput] | list[PreTokenizedInput] = None, + videos: VideoInput | None = None, + **kwargs: Unpack[Qwen2_5_VLProcessorKwargs], + ) -> BatchFeature: + r""" + Returns: + [`BatchFeature`]: A [`BatchFeature`] with the following fields: + + - **input_ids** -- List of token ids to be fed to a model. Returned when `text` is not `None`. + - **attention_mask** -- List of indices specifying which tokens should be attended to by the model (when + `return_attention_mask=True` or if *"attention_mask"* is in `self.model_input_names` and if `text` is not + `None`). + - **pixel_values** -- Pixel values to be fed to a model. Returned when `images` is not `None`. + - **pixel_values_videos** -- Pixel values of videos to be fed to a model. Returned when `videos` is not `None`. + - **image_grid_thw** -- List of image 3D grid in LLM. Returned when `images` is not `None`. + - **video_grid_thw** -- List of video 3D grid in LLM. Returned when `videos` is not `None`. + - **second_per_grid_ts** -- List of video seconds per time grid. Returned when `videos` is not `None`. + """ + output_kwargs = self._merge_kwargs( + Qwen2_5_VLProcessorKwargs, + tokenizer_init_kwargs=self.tokenizer.init_kwargs, + **kwargs, + ) + + image_inputs = videos_inputs = {} + if images is not None: + image_inputs = self.image_processor(images=images, **output_kwargs["images_kwargs"]) + image_grid_thw = image_inputs["image_grid_thw"] + + if videos is not None: + videos_inputs = self.video_processor(videos=videos, **output_kwargs["videos_kwargs"]) + video_grid_thw = videos_inputs["video_grid_thw"] + + # Get video metadata + if not kwargs.get("return_metadata"): + video_metadata = videos_inputs.pop("video_metadata") + else: + video_metadata = videos_inputs["video_metadata"] + + fps = [metadata.sampled_fps for metadata in video_metadata] + + if isinstance(fps, (int, float)): + second_per_grid_ts = [self.video_processor.temporal_patch_size / fps] * len(video_grid_thw) + elif hasattr(fps, "__len__") and len(fps) == len(video_grid_thw): + second_per_grid_ts = [self.video_processor.temporal_patch_size / tmp for tmp in fps] + else: + raise ValueError( + f"The length of fps ({len(fps) if hasattr(fps, '__len__') else fps}) must be equal to the length of video_grid_thw ({len(video_grid_thw)}) or fps should be a single number." + ) + videos_inputs.update({"second_per_grid_ts": second_per_grid_ts}) + + if not isinstance(text, list): + text = [text] + + text = text.copy() # below lines change text in-place + if images is not None: + merge_length = self.image_processor.merge_size**2 + index = 0 + for i in range(len(text)): + while self.image_token in text[i]: + num_image_tokens = image_grid_thw[index].prod() // merge_length + text[i] = text[i].replace(self.image_token, "<|placeholder|>" * num_image_tokens, 1) + index += 1 + text[i] = text[i].replace("<|placeholder|>", self.image_token) + + if videos is not None: + merge_length = self.video_processor.merge_size**2 + index = 0 + for i in range(len(text)): + while self.video_token in text[i]: + num_video_tokens = video_grid_thw[index].prod() // merge_length + text[i] = text[i].replace(self.video_token, "<|placeholder|>" * num_video_tokens, 1) + index += 1 + text[i] = text[i].replace("<|placeholder|>", self.video_token) + + return_tensors = output_kwargs["text_kwargs"].pop("return_tensors", None) + return_mm_token_type_ids = output_kwargs["text_kwargs"].pop("return_mm_token_type_ids", None) + text_inputs = self.tokenizer(text, **output_kwargs["text_kwargs"]) + self._check_special_mm_tokens(text, text_inputs, modalities=["image", "video"]) + + if return_mm_token_type_ids: + array_ids = np.array(text_inputs["input_ids"]) + mm_token_type_ids = np.zeros_like(text_inputs["input_ids"]) + mm_token_type_ids[array_ids == self.image_token_id] = 1 + mm_token_type_ids[array_ids == self.video_token_id] = 2 + text_inputs["mm_token_type_ids"] = mm_token_type_ids.tolist() + + return BatchFeature(data={**text_inputs, **image_inputs, **videos_inputs}, tensor_type=return_tensors) + + def _get_num_multimodal_tokens(self, image_sizes=None, video_sizes=None, **kwargs): + """ + Computes the number of placeholder tokens needed for multimodal inputs with the given sizes. + Args: + image_sizes (`list[list[int]]`, *optional*): + The input sizes formatted as (height, width) per each image. + video_sizes (`list[list[int]]`, *optional*): + The input sizes formatted as (num_frames, height, width) per each video. + Returns: + `MultiModalData`: A `MultiModalData` object holding number of tokens per each of the provided + input modalities, along with other useful data. + """ + + vision_data = {} + if image_sizes is not None: + images_kwargs = Qwen2_5_VLProcessorKwargs._defaults.get("images_kwargs", {}) + images_kwargs.update(kwargs) + merge_size = images_kwargs.get("merge_size", None) or self.image_processor.merge_size + + num_image_patches = [ + self.image_processor.get_number_of_image_patches(*image_size, images_kwargs) + for image_size in image_sizes + ] + num_image_tokens = [(num_patches // merge_size**2) for num_patches in num_image_patches] + vision_data.update({"num_image_tokens": num_image_tokens, "num_image_patches": num_image_patches}) + + if video_sizes is not None: + videos_kwargs = Qwen2_5_VLProcessorKwargs._defaults.get("videos_kwargs", {}) + videos_kwargs.update(kwargs) + num_video_patches = [ + self.video_processor.get_number_of_video_patches(*video_size, videos_kwargs) + for video_size in video_sizes + ] + num_video_tokens = [(num_patches // merge_size**2) for num_patches in num_video_patches] + vision_data["num_video_tokens"] = num_video_tokens + + return MultiModalData(**vision_data) + + +__all__ = [ + "Qwen2_5_VLConfig", + "Qwen2_5_VLTextConfig", + "Qwen2_5_VLForConditionalGeneration", + "Qwen2_5_VLModel", + "Qwen2_5_VLPreTrainedModel", + "Qwen2_5_VLProcessor", + "Qwen2_5_VLTextModel", # noqa: F822 +] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/qwen2_5_vl/processing_qwen2_5_vl.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/qwen2_5_vl/processing_qwen2_5_vl.py new file mode 100644 index 0000000000000000000000000000000000000000..6082653751e1c11975bfb682bce0ce18fd24018d --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/qwen2_5_vl/processing_qwen2_5_vl.py @@ -0,0 +1,232 @@ +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# This file was automatically generated from src/transformers/models/qwen2_5_vl/modular_qwen2_5_vl.py. +# Do NOT edit this file manually as any edits will be overwritten by the generation of +# the file from the modular. If any change should be done, please apply the change to the +# modular_qwen2_5_vl.py file directly. One of our CI enforces this. +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# Copyright 2025 The Qwen Team and The HuggingFace Inc. team. All rights reserved. +# +# This code is based on EleutherAI's GPT-NeoX library and the GPT-NeoX +# and OPT implementations in this library. It has been modified from its +# original forms to accommodate minor architectural differences compared +# to GPT-NeoX and OPT used by the Meta AI team that trained the model. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import numpy as np + +from ...feature_extraction_utils import BatchFeature +from ...image_utils import ImageInput +from ...processing_utils import MultiModalData, ProcessingKwargs, ProcessorMixin, Unpack +from ...tokenization_utils_base import PreTokenizedInput, TextInput +from ...utils import auto_docstring +from ...video_utils import VideoInput + + +class Qwen2_5_VLProcessorKwargs(ProcessingKwargs, total=False): + _defaults = { + "text_kwargs": { + "padding": False, + "return_mm_token_type_ids": True, + }, + "videos_kwargs": {"return_metadata": True}, + } + + +@auto_docstring +class Qwen2_5_VLProcessor(ProcessorMixin): + def __init__(self, image_processor=None, tokenizer=None, video_processor=None, chat_template=None, **kwargs): + self.image_token = "<|image_pad|>" if not hasattr(tokenizer, "image_token") else tokenizer.image_token + self.video_token = "<|video_pad|>" if not hasattr(tokenizer, "video_token") else tokenizer.video_token + self.image_token_id = ( + tokenizer.image_token_id + if getattr(tokenizer, "image_token_id", None) + else tokenizer.convert_tokens_to_ids(self.image_token) + ) + self.video_token_id = ( + tokenizer.video_token_id + if getattr(tokenizer, "video_token_id", None) + else tokenizer.convert_tokens_to_ids(self.video_token) + ) + super().__init__(image_processor, tokenizer, video_processor, chat_template=chat_template) + + @auto_docstring + def __call__( + self, + images: ImageInput | None = None, + text: TextInput | PreTokenizedInput | list[TextInput] | list[PreTokenizedInput] = None, + videos: VideoInput | None = None, + **kwargs: Unpack[Qwen2_5_VLProcessorKwargs], + ) -> BatchFeature: + r""" + Returns: + [`BatchFeature`]: A [`BatchFeature`] with the following fields: + + - **input_ids** -- List of token ids to be fed to a model. Returned when `text` is not `None`. + - **attention_mask** -- List of indices specifying which tokens should be attended to by the model (when + `return_attention_mask=True` or if *"attention_mask"* is in `self.model_input_names` and if `text` is not + `None`). + - **pixel_values** -- Pixel values to be fed to a model. Returned when `images` is not `None`. + - **pixel_values_videos** -- Pixel values of videos to be fed to a model. Returned when `videos` is not `None`. + - **image_grid_thw** -- List of image 3D grid in LLM. Returned when `images` is not `None`. + - **video_grid_thw** -- List of video 3D grid in LLM. Returned when `videos` is not `None`. + - **second_per_grid_ts** -- List of video seconds per time grid. Returned when `videos` is not `None`. + """ + output_kwargs = self._merge_kwargs( + Qwen2_5_VLProcessorKwargs, + tokenizer_init_kwargs=self.tokenizer.init_kwargs, + **kwargs, + ) + + image_inputs = videos_inputs = {} + if images is not None: + image_inputs = self.image_processor(images=images, **output_kwargs["images_kwargs"]) + image_grid_thw = image_inputs["image_grid_thw"] + + if videos is not None: + videos_inputs = self.video_processor(videos=videos, **output_kwargs["videos_kwargs"]) + video_grid_thw = videos_inputs["video_grid_thw"] + + # Get video metadata + if not kwargs.get("return_metadata"): + video_metadata = videos_inputs.pop("video_metadata") + else: + video_metadata = videos_inputs["video_metadata"] + + fps = [metadata.sampled_fps for metadata in video_metadata] + + if isinstance(fps, (int, float)): + second_per_grid_ts = [self.video_processor.temporal_patch_size / fps] * len(video_grid_thw) + elif hasattr(fps, "__len__") and len(fps) == len(video_grid_thw): + second_per_grid_ts = [self.video_processor.temporal_patch_size / tmp for tmp in fps] + else: + raise ValueError( + f"The length of fps ({len(fps) if hasattr(fps, '__len__') else fps}) must be equal to the length of video_grid_thw ({len(video_grid_thw)}) or fps should be a single number." + ) + videos_inputs.update({"second_per_grid_ts": second_per_grid_ts}) + + if not isinstance(text, list): + text = [text] + + text = text.copy() # below lines change text in-place + if images is not None: + merge_length = self.image_processor.merge_size**2 + index = 0 + for i in range(len(text)): + while self.image_token in text[i]: + num_image_tokens = image_grid_thw[index].prod() // merge_length + text[i] = text[i].replace(self.image_token, "<|placeholder|>" * num_image_tokens, 1) + index += 1 + text[i] = text[i].replace("<|placeholder|>", self.image_token) + + if videos is not None: + merge_length = self.video_processor.merge_size**2 + index = 0 + for i in range(len(text)): + while self.video_token in text[i]: + num_video_tokens = video_grid_thw[index].prod() // merge_length + text[i] = text[i].replace(self.video_token, "<|placeholder|>" * num_video_tokens, 1) + index += 1 + text[i] = text[i].replace("<|placeholder|>", self.video_token) + + return_tensors = output_kwargs["text_kwargs"].pop("return_tensors", None) + return_mm_token_type_ids = output_kwargs["text_kwargs"].pop("return_mm_token_type_ids", None) + text_inputs = self.tokenizer(text, **output_kwargs["text_kwargs"]) + self._check_special_mm_tokens(text, text_inputs, modalities=["image", "video"]) + + if return_mm_token_type_ids: + array_ids = np.array(text_inputs["input_ids"]) + mm_token_type_ids = np.zeros_like(text_inputs["input_ids"]) + mm_token_type_ids[array_ids == self.image_token_id] = 1 + mm_token_type_ids[array_ids == self.video_token_id] = 2 + text_inputs["mm_token_type_ids"] = mm_token_type_ids.tolist() + + return BatchFeature(data={**text_inputs, **image_inputs, **videos_inputs}, tensor_type=return_tensors) + + def _get_num_multimodal_tokens(self, image_sizes=None, video_sizes=None, **kwargs): + """ + Computes the number of placeholder tokens needed for multimodal inputs with the given sizes. + Args: + image_sizes (`list[list[int]]`, *optional*): + The input sizes formatted as (height, width) per each image. + video_sizes (`list[list[int]]`, *optional*): + The input sizes formatted as (num_frames, height, width) per each video. + Returns: + `MultiModalData`: A `MultiModalData` object holding number of tokens per each of the provided + input modalities, along with other useful data. + """ + + vision_data = {} + if image_sizes is not None: + images_kwargs = Qwen2_5_VLProcessorKwargs._defaults.get("images_kwargs", {}) + images_kwargs.update(kwargs) + merge_size = images_kwargs.get("merge_size", None) or self.image_processor.merge_size + + num_image_patches = [ + self.image_processor.get_number_of_image_patches(*image_size, images_kwargs) + for image_size in image_sizes + ] + num_image_tokens = [(num_patches // merge_size**2) for num_patches in num_image_patches] + vision_data.update({"num_image_tokens": num_image_tokens, "num_image_patches": num_image_patches}) + + if video_sizes is not None: + videos_kwargs = Qwen2_5_VLProcessorKwargs._defaults.get("videos_kwargs", {}) + videos_kwargs.update(kwargs) + num_video_patches = [ + self.video_processor.get_number_of_video_patches(*video_size, videos_kwargs) + for video_size in video_sizes + ] + num_video_tokens = [(num_patches // merge_size**2) for num_patches in num_video_patches] + vision_data["num_video_tokens"] = num_video_tokens + + return MultiModalData(**vision_data) + + def post_process_image_text_to_text( + self, generated_outputs, skip_special_tokens=True, clean_up_tokenization_spaces=False, **kwargs + ): + """ + Post-process the output of the model to decode the text. + + Args: + generated_outputs (`torch.Tensor` or `np.ndarray`): + The output of the model `generate` function. The output is expected to be a tensor of shape `(batch_size, sequence_length)` + or `(sequence_length,)`. + skip_special_tokens (`bool`, *optional*, defaults to `True`): + Whether or not to remove special tokens in the output. Argument passed to the tokenizer's `batch_decode` method. + clean_up_tokenization_spaces (`bool`, *optional*, defaults to `False`): + Whether or not to clean up the tokenization spaces. Argument passed to the tokenizer's `batch_decode` method. + **kwargs: + Additional arguments to be passed to the tokenizer's `batch_decode method`. + + Returns: + `list[str]`: The decoded text. + """ + return self.tokenizer.batch_decode( + generated_outputs, + skip_special_tokens=skip_special_tokens, + clean_up_tokenization_spaces=clean_up_tokenization_spaces, + **kwargs, + ) + + @property + def model_input_names(self): + tokenizer_input_names = self.tokenizer.model_input_names + image_processor_input_names = self.image_processor.model_input_names + video_processor_input_names = self.video_processor.model_input_names + names_from_processor = list( + dict.fromkeys(tokenizer_input_names + image_processor_input_names + video_processor_input_names) + ) + return names_from_processor + ["second_per_grid_ts", "mm_token_type_ids"] + + +__all__ = ["Qwen2_5_VLProcessor"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/qwen2_audio/__init__.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/qwen2_audio/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..b126d712bd469e57188316a0b0ba127f31ddfd2e --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/qwen2_audio/__init__.py @@ -0,0 +1,28 @@ +# Copyright 2024 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from typing import TYPE_CHECKING + +from ...utils import _LazyModule +from ...utils.import_utils import define_import_structure + + +if TYPE_CHECKING: + from .configuration_qwen2_audio import * + from .modeling_qwen2_audio import * + from .processing_qwen2_audio import * +else: + import sys + + _file = globals()["__file__"] + sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__) diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/qwen2_audio/configuration_qwen2_audio.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/qwen2_audio/configuration_qwen2_audio.py new file mode 100644 index 0000000000000000000000000000000000000000..061d200fe5ba43e5a1122179e3580555515d808d --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/qwen2_audio/configuration_qwen2_audio.py @@ -0,0 +1,202 @@ +# Copyright 2024 Microsoft Research & University of Wisconsin-Madison and the HuggingFace Inc. team. All rights reserved. +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""Qwen2Audio model configuration""" + +from ...configuration_utils import PreTrainedConfig +from ...utils import logging +from ..auto import CONFIG_MAPPING, AutoConfig + + +logger = logging.get_logger(__name__) + + +class Qwen2AudioEncoderConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`Qwen2AudioEncoder`]. It is used to instantiate a + Qwen2-Audio audio encoder according to the specified arguments, defining the model architecture. Instantiating a + configuration with the defaults will yield a similar configuration to that of the audio encoder of the Qwen2-Audio + architecture. + + e.g. [Qwen/Qwen2-Audio-7B](https://huggingface.co/Qwen/Qwen2-Audio-7B) + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + num_mel_bins (`int`, *optional*, defaults to 128): + Number of mel features used per input features. Should correspond to the value used in the + `Qwen2AudioProcessor` class. + encoder_layers (`int`, *optional*, defaults to 32): + Number of encoder layers. + encoder_attention_heads (`int`, *optional*, defaults to 20): + Number of attention heads for each attention layer in the Transformer encoder. + encoder_ffn_dim (`int`, *optional*, defaults to 5120): + Dimensionality of the "intermediate" (often named feed-forward) layer in encoder. + encoder_layerdrop (`float`, *optional*, defaults to 0.0): + The LayerDrop probability for the encoder. See the [LayerDrop paper](see https://huggingface.co/papers/1909.11556) + for more details. + d_model (`int`, *optional*, defaults to 1280): + Dimensionality of the layers. + dropout (`float`, *optional*, defaults to 0.0): + The dropout probability for all fully connected layers in the embeddings, encoder, and pooler. + attention_dropout (`float`, *optional*, defaults to 0.0): + The dropout ratio for the attention probabilities. + activation_function (`str`, *optional*, defaults to `"gelu"`): + The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`, + `"relu"`, `"silu"` and `"gelu_new"` are supported. + activation_dropout (`float`, *optional*, defaults to 0.0): + The dropout ratio for activations inside the fully connected layer. + scale_embedding (`bool`, *optional*, defaults to `False`): + Scale embeddings by diving by sqrt(d_model). + initializer_range (`float`, *optional*, defaults to 0.02): + The standard deviation of the truncated_normal_initializer for initializing all weight matrices. + max_source_positions (`int`, *optional*, defaults to 1500): + The maximum sequence length of log-mel filter-bank features that this model might ever be used with. + + Example: + + ```python + >>> from transformers import Qwen2AudioEncoderConfig, Qwen2AudioEncoder + + >>> # Initializing a Qwen2AudioEncoderConfig + >>> configuration = Qwen2AudioEncoderConfig() + + >>> # Initializing a Qwen2AudioEncoder (with random weights) + >>> model = Qwen2AudioEncoder(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "qwen2_audio_encoder" + + def __init__( + self, + num_mel_bins=128, + encoder_layers=32, + encoder_attention_heads=20, + encoder_ffn_dim=5120, + encoder_layerdrop=0.0, + d_model=1280, + dropout=0.0, + attention_dropout=0.0, + activation_function="gelu", + activation_dropout=0.0, + scale_embedding=False, + initializer_range=0.02, + max_source_positions=1500, + **kwargs, + ): + super().__init__(**kwargs) + + self.num_mel_bins = num_mel_bins + self.d_model = d_model + self.encoder_layers = encoder_layers + self.encoder_attention_heads = encoder_attention_heads + self.encoder_ffn_dim = encoder_ffn_dim + self.dropout = dropout + self.attention_dropout = attention_dropout + self.activation_function = activation_function + self.activation_dropout = activation_dropout + self.encoder_layerdrop = encoder_layerdrop + self.num_hidden_layers = encoder_layers + self.initializer_range = initializer_range + self.scale_embedding = scale_embedding # scale factor will be sqrt(d_model) if True + self.max_source_positions = max_source_positions + + +class Qwen2AudioConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`Qwen2AudioForConditionalGeneration`]. It is used to instantiate an + Qwen2-Audio model according to the specified arguments, defining the model architecture. Instantiating a configuration + with the defaults will yield a similar configuration to that of the Qwen2-Audio. + + e.g. [Qwen/Qwen2-Audio-7B](https://huggingface.co/Qwen/Qwen2-Audio-7B) + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + audio_config (`Union[AutoConfig, dict]`, *optional*, defaults to `CLIPVisionConfig`): + The config object or dictionary of the audio backbone. + text_config (`Union[AutoConfig, dict]`, *optional*, defaults to `LlamaConfig`): + The config object or dictionary of the text backbone. + audio_token_index (`int`, *optional*, defaults to 151646): + The image token index to encode the image prompt. + + Example: + + ```python + >>> from transformers import Qwen2AudioForConditionalGeneration, Qwen2AudioConfig, Qwen2AudioEncoderConfig, Qwen2Config + + >>> # Initializing a Qwen2AudioEncoder config + >>> audio_config = Qwen2AudioEncoderConfig() + + >>> # Initializing a Qwen2 config + >>> text_config = Qwen2Config() + + >>> # Initializing a Qwen2Audio configuration + >>> configuration = Qwen2AudioConfig(audio_config, text_config) + + >>> # Initializing a model from the qwen2-audio style configuration + >>> model = Qwen2AudioForConditionalGeneration(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "qwen2_audio" + attribute_map = { + "audio_token_id": "audio_token_index", + } + sub_configs = {"text_config": AutoConfig, "audio_config": AutoConfig} + + def __init__( + self, + audio_config=None, + text_config=None, + audio_token_index=151646, + **kwargs, + ): + self.audio_token_index = audio_token_index + + if isinstance(audio_config, dict): + audio_config["model_type"] = audio_config.get("model_type", "qwen2_audio_encoder") + audio_config = CONFIG_MAPPING[audio_config["model_type"]](**audio_config) + elif audio_config is None: + audio_config = CONFIG_MAPPING["qwen2_audio_encoder"]( + d_model=1280, + encoder_attention_heads=20, + encoder_ffn_dim=5120, + encoder_layerdrop=0.0, + encoder_layers=32, + num_mel_bins=128, + max_source_positions=1500, + scale_embedding=False, + activation_function="gelu", + ) + + self.audio_config = audio_config + + if isinstance(text_config, dict): + text_config["model_type"] = text_config.get("model_type", "qwen2") + text_config = CONFIG_MAPPING[text_config["model_type"]](**text_config) + elif text_config is None: + text_config = CONFIG_MAPPING["qwen2"]() + + self.text_config = text_config + + super().__init__(**kwargs) + + +__all__ = ["Qwen2AudioConfig", "Qwen2AudioEncoderConfig"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/qwen2_audio/modeling_qwen2_audio.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/qwen2_audio/modeling_qwen2_audio.py new file mode 100644 index 0000000000000000000000000000000000000000..f3f94c933881f03901baf9ba7f01bf97c91c5cb1 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/qwen2_audio/modeling_qwen2_audio.py @@ -0,0 +1,860 @@ +# Copyright 2024 the HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""PyTorch Qwen2Audio model.""" + +import math +from collections.abc import Callable +from dataclasses import dataclass + +import torch +from torch import nn + +from ...activations import ACT2FN +from ...cache_utils import Cache +from ...generation import GenerationMixin +from ...masking_utils import create_bidirectional_mask +from ...modeling_layers import GradientCheckpointingLayer +from ...modeling_outputs import BaseModelOutput, ModelOutput +from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel +from ...utils import auto_docstring, is_torchdynamo_compiling, logging, torch_compilable_check +from ..auto import AutoModel, AutoModelForCausalLM +from .configuration_qwen2_audio import Qwen2AudioConfig, Qwen2AudioEncoderConfig + + +logger = logging.get_logger(__name__) + + +@dataclass +@auto_docstring( + custom_intro=""" + Base class for Qwen2Audio causal language model (or autoregressive) outputs. + """ +) +class Qwen2AudioCausalLMOutputWithPast(ModelOutput): + r""" + loss (`torch.FloatTensor` of shape `(1,)`, *optional*, returned when `labels` is provided): + Language modeling loss (for next-token prediction). + logits (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.vocab_size)`): + Prediction scores of the language modeling head (scores for each vocabulary token before SoftMax). + past_key_values (`Cache`, *optional*, returned when `use_cache=True` is passed or when `config.use_cache=True`): + Pre-computed hidden-states that can be used to speed up auto-regressive (sequential) decoding. There are + two sets of pre-computed hidden-states: key and values states in the self-attention blocks. + The `past_key_values` are returned when `use_cache=True` is passed or when `config.use_cache=True`. + It is a [`~cache_utils.Cache`] instance. + + If `past_key_values` are used, the user can optionally input only the last `input_ids` (those + that don't have their past key value states given to this model) of shape `(batch_size, 1)` instead of + all `input_ids` of shape `(batch_size, sequence_length)`. + attention_mask (`torch.FloatTensor`, *optional*): + Attentions mask, used to update attention mask and position_ids. + """ + + loss: torch.FloatTensor | None = None + logits: torch.FloatTensor | None = None + past_key_values: Cache | None = None + hidden_states: tuple[torch.FloatTensor] | None = None + attentions: tuple[torch.FloatTensor] | None = None + attention_mask: torch.FloatTensor | None = None + + +# Copied from transformers.models.whisper.modeling_whisper.eager_attention_forward +def eager_attention_forward( + module: nn.Module, + query: torch.Tensor, + key: torch.Tensor, + value: torch.Tensor, + attention_mask: torch.Tensor | None, + scaling: float | None = None, + dropout: float = 0.0, + **kwargs, +): + if scaling is None: + scaling = query.size(-1) ** -0.5 + + attn_weights = torch.matmul(query, key.transpose(2, 3)) * scaling + if attention_mask is not None: + attn_weights = attn_weights + attention_mask + + attn_weights = nn.functional.softmax(attn_weights, dim=-1) + + attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training) + attn_output = torch.matmul(attn_weights, value) + attn_output = attn_output.transpose(1, 2).contiguous() + + return attn_output, attn_weights + + +class Qwen2AudioAttention(nn.Module): + """Multi-headed attention from 'Attention Is All You Need' paper""" + + # Copied from transformers.models.whisper.modeling_whisper.WhisperAttention.__init__ with Whisper->Qwen2Audio + def __init__( + self, + embed_dim: int, + num_heads: int, + dropout: float = 0.0, + is_decoder: bool = False, + bias: bool = True, + is_causal: bool = False, + layer_idx: int | None = None, + config: Qwen2AudioConfig | None = None, + ): + super().__init__() + self.embed_dim = embed_dim + self.num_heads = num_heads + self.dropout = dropout + self.head_dim = embed_dim // num_heads + self.config = config + + if (self.head_dim * num_heads) != self.embed_dim: + raise ValueError( + f"embed_dim must be divisible by num_heads (got `embed_dim`: {self.embed_dim}" + f" and `num_heads`: {num_heads})." + ) + self.scaling = self.head_dim**-0.5 + self.is_decoder = is_decoder + self.is_causal = is_causal + + if layer_idx is None and is_decoder: + logger.warning_once( + f"Instantiating a decoder {self.__class__.__name__} without passing `layer_idx` is not recommended and " + "will to errors during the forward call, if caching is used. Please make sure to provide a `layer_idx` " + "when creating this class." + ) + self.layer_idx = layer_idx + + self.k_proj = nn.Linear(embed_dim, embed_dim, bias=False) + self.v_proj = nn.Linear(embed_dim, embed_dim, bias=bias) + self.q_proj = nn.Linear(embed_dim, embed_dim, bias=bias) + self.out_proj = nn.Linear(embed_dim, embed_dim, bias=bias) + + def _shape(self, tensor: torch.Tensor, seq_len: int, bsz: int): + return tensor.view(bsz, seq_len, self.num_heads, self.head_dim).transpose(1, 2).contiguous() + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.Tensor | None = None, + output_attentions: bool = False, + **kwargs, + ) -> tuple[torch.Tensor, torch.Tensor | None, tuple[torch.Tensor] | None]: + """Input shape: Batch x Time x Channel""" + + bsz, tgt_len, _ = hidden_states.size() + + # Scaling is susceptible to floating point arithmetics' inprecisions + # which can lead to different results (this is dependent from model + # to model, e.g. whisper is one such case). We therefore keep the + # original order of scaling to follow the original implementation + # and enforce no scaling (1.0) in the attention call below. + query_states = self._shape(self.q_proj(hidden_states) * self.scaling, tgt_len, bsz) + key_states = self._shape(self.k_proj(hidden_states), -1, bsz) + value_states = self._shape(self.v_proj(hidden_states), -1, bsz) + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, eager_attention_forward + ) + + attn_output, attn_weights = attention_interface( + self, + query_states, + key_states, + value_states, + attention_mask, + dropout=0.0 if not self.training else self.dropout, + scaling=1.0, + output_attentions=output_attentions, + **kwargs, + ) + + attn_output = attn_output.reshape(bsz, tgt_len, -1).contiguous() + attn_output = self.out_proj(attn_output) + + return attn_output, attn_weights + + +# Copied from transformers.models.whisper.modeling_whisper.WhisperEncoderLayer with Whisper->Qwen2Audio, WHISPER->QWEN2AUDIO +class Qwen2AudioEncoderLayer(GradientCheckpointingLayer): + def __init__(self, config: Qwen2AudioConfig): + super().__init__() + self.embed_dim = config.d_model + + self.self_attn = Qwen2AudioAttention( + embed_dim=self.embed_dim, + num_heads=config.encoder_attention_heads, + dropout=config.attention_dropout, + config=config, + ) + self.self_attn_layer_norm = nn.LayerNorm(self.embed_dim) + self.dropout = config.dropout + self.activation_fn = ACT2FN[config.activation_function] + self.activation_dropout = config.activation_dropout + self.fc1 = nn.Linear(self.embed_dim, config.encoder_ffn_dim) + self.fc2 = nn.Linear(config.encoder_ffn_dim, self.embed_dim) + self.final_layer_norm = nn.LayerNorm(self.embed_dim) + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.Tensor, + output_attentions: bool = False, + ) -> torch.Tensor: + """ + Args: + hidden_states (`torch.FloatTensor`): input to the layer of shape `(batch, seq_len, embed_dim)` + attention_mask (`torch.FloatTensor`): attention mask of size + `(batch, 1, tgt_len, src_len)` where padding elements are indicated by very large negative values. + output_attentions (`bool`, *optional*): + Whether or not to return the attentions tensors of all attention layers. See `attentions` under + returned tensors for more detail. + """ + residual = hidden_states + hidden_states = self.self_attn_layer_norm(hidden_states) + hidden_states, attn_weights = self.self_attn( + hidden_states=hidden_states, + attention_mask=attention_mask, + output_attentions=output_attentions, + ) + hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training) + hidden_states = residual + hidden_states + + residual = hidden_states + hidden_states = self.final_layer_norm(hidden_states) + hidden_states = self.activation_fn(self.fc1(hidden_states)) + hidden_states = nn.functional.dropout(hidden_states, p=self.activation_dropout, training=self.training) + hidden_states = self.fc2(hidden_states) + hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training) + hidden_states = residual + hidden_states + + if hidden_states.dtype == torch.float16: + clamp_value = torch.finfo(hidden_states.dtype).max - 1000 + hidden_states = torch.clamp(hidden_states, min=-clamp_value, max=clamp_value) + + return hidden_states, attn_weights + + +@auto_docstring +class Qwen2AudioPreTrainedModel(PreTrainedModel): + config: Qwen2AudioConfig + base_model_prefix = "model" + input_modalities = ("audio", "text") + supports_gradient_checkpointing = True + _no_split_modules = ["Qwen2AudioAttention"] + _skip_keys_device_placement = "past_key_values" + _supports_flash_attn = True + _supports_sdpa = True + + +@auto_docstring( + custom_intro=""" + The audio model from Qwen2Audio without any head or projection on top. + """ +) +# Copied from transformers.models.whisper.modeling_whisper.WhisperEncoder with Whisper->Qwen2Audio +class Qwen2AudioEncoder(Qwen2AudioPreTrainedModel): + """ + Transformer encoder consisting of *config.encoder_layers* self attention layers. Each layer is a + [`Qwen2AudioEncoderLayer`]. + + Args: + config: Qwen2AudioEncoderConfig + """ + + # Ignore copy + config: Qwen2AudioEncoderConfig + main_input_name = "input_features" + input_modalities = "audio" + _no_split_modules = ["Qwen2AudioEncoderLayer"] + + def __init__(self, config: Qwen2AudioEncoderConfig): + super().__init__(config) + self.dropout = config.dropout + self.layerdrop = config.encoder_layerdrop + + embed_dim = config.d_model + self.num_mel_bins = config.num_mel_bins + self.max_source_positions = config.max_source_positions + self.embed_scale = math.sqrt(embed_dim) if config.scale_embedding else 1.0 + + self.conv1 = nn.Conv1d(self.num_mel_bins, embed_dim, kernel_size=3, padding=1) + self.conv2 = nn.Conv1d(embed_dim, embed_dim, kernel_size=3, stride=2, padding=1) + + self.embed_positions = nn.Embedding(self.max_source_positions, embed_dim) + self.embed_positions.requires_grad_(False) + + self.layers = nn.ModuleList([Qwen2AudioEncoderLayer(config) for _ in range(config.encoder_layers)]) + self.layer_norm = nn.LayerNorm(config.d_model) + # Ignore copy + self.avg_pooler = nn.AvgPool1d(2, stride=2) + + self.gradient_checkpointing = False + # Initialize weights and apply final processing + self.post_init() + + def _freeze_parameters(self): + for param in self.parameters(): + param.requires_grad = False + self._requires_grad = False + + def get_input_embeddings(self) -> nn.Module: + return self.conv1 + + def set_input_embeddings(self, value: nn.Module): + self.conv1 = value + + def forward( + self, + input_features, + attention_mask=None, + output_attentions=None, + output_hidden_states=None, + return_dict=None, + **kwargs, + ): + r""" + Args: + attention_mask (`torch.Tensor`)`, *optional*): + Qwen2Audio does not support masking of the `input_features`, this argument is preserved for compatibility, + but it is not used. By default the silence in the input log mel spectrogram are ignored. + output_attentions (`bool`, *optional*): + Whether or not to return the attentions tensors of all attention layers. See `attentions` under + returned tensors for more detail. + output_hidden_states (`bool`, *optional*): + Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors + for more detail. + return_dict (`bool`, *optional*): + Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple. + """ + + expected_seq_length = self.config.max_source_positions * self.conv1.stride[0] * self.conv2.stride[0] + if input_features.shape[-1] != expected_seq_length: + raise ValueError( + f"Qwen2Audio expects the mel input features to be of length {expected_seq_length}, but found {input_features.shape[-1]}. Make sure to pad the input mel features to {expected_seq_length}." + ) + + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + # Ignore copy + input_features = input_features.to(dtype=self.conv1.weight.dtype, device=self.conv1.weight.device) + + inputs_embeds = nn.functional.gelu(self.conv1(input_features)) + inputs_embeds = nn.functional.gelu(self.conv2(inputs_embeds)) + + inputs_embeds = inputs_embeds.permute(0, 2, 1) + embed_pos = self.embed_positions.weight + + hidden_states = inputs_embeds + embed_pos + hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training) + + encoder_states = () if output_hidden_states else None + all_attentions = () if output_attentions else None + + for idx, encoder_layer in enumerate(self.layers): + if output_hidden_states: + encoder_states = encoder_states + (hidden_states,) + # add LayerDrop (see https://huggingface.co/papers/1909.11556 for description) + to_drop = False + if self.training: + dropout_probability = torch.rand([]) + if dropout_probability < self.layerdrop: # skip the layer + to_drop = True + + # Ignore copy + if to_drop: + layer_outputs = (None, None) + else: + layer_outputs = encoder_layer( + hidden_states, + attention_mask, + output_attentions=output_attentions, + ) + + hidden_states = layer_outputs[0] + + if output_attentions: + all_attentions = all_attentions + (layer_outputs[1],) + + # Ignore copy + hidden_states = hidden_states.permute(0, 2, 1) + hidden_states = self.avg_pooler(hidden_states) + hidden_states = hidden_states.permute(0, 2, 1) + + hidden_states = self.layer_norm(hidden_states) + if output_hidden_states: + encoder_states = encoder_states + (hidden_states,) + + if not return_dict: + return tuple(v for v in [hidden_states, encoder_states, all_attentions] if v is not None) + return BaseModelOutput( + last_hidden_state=hidden_states, hidden_states=encoder_states, attentions=all_attentions + ) + + # Ignore copy + def _get_feat_extract_output_lengths(self, input_lengths: torch.LongTensor): + """ + Computes the output length of the convolutional layers and the output length of the audio encoder + """ + input_lengths = (input_lengths - 1) // 2 + 1 + output_lengths = (input_lengths - 2) // 2 + 1 + return input_lengths, output_lengths + + +class Qwen2AudioMultiModalProjector(nn.Module): + def __init__(self, config: Qwen2AudioConfig): + super().__init__() + self.linear = nn.Linear(config.audio_config.d_model, config.text_config.hidden_size, bias=True) + + def forward(self, audio_features): + hidden_states = self.linear(audio_features) + return hidden_states + + +@auto_docstring( + custom_intro=""" + The QWEN2AUDIO model which consists of a audio backbone and a language model. + """ +) +class Qwen2AudioForConditionalGeneration(Qwen2AudioPreTrainedModel, GenerationMixin): + def __init__(self, config: Qwen2AudioConfig): + super().__init__(config) + self.audio_tower = AutoModel.from_config(config.audio_config) # Usually a `Qwen2AudioEncoder` instance + + self.multi_modal_projector = Qwen2AudioMultiModalProjector(config) + self.vocab_size = config.text_config.vocab_size + self.language_model = AutoModelForCausalLM.from_config(config.text_config) + + self.pad_token_id = ( + self.config.text_config.pad_token_id if self.config.text_config.pad_token_id is not None else -1 + ) + self._padding_side = "left" # set it to left by default, user can use setter to change padding_sides + self.post_init() + + @property + def padding_side(self): + return self._padding_side + + @padding_side.setter + def padding_side(self, padding_side: str): + if padding_side not in ["left", "right"]: + raise ValueError(f"{padding_side} is not `left` or `right`.") + self._padding_side = padding_side + + def get_input_embeddings(self): + return self.language_model.get_input_embeddings() + + def set_input_embeddings(self, value): + self.language_model.set_input_embeddings(value) + + def get_output_embeddings(self): + return self.language_model.get_output_embeddings() + + def set_output_embeddings(self, new_embeddings): + self.language_model.set_output_embeddings(new_embeddings) + + def set_decoder(self, decoder): + self.language_model.set_decoder(decoder) + + def get_decoder(self): + return self.language_model.get_decoder() + + def _merge_input_ids_with_audio_features( + self, audio_features, num_audio_tokens, inputs_embeds, input_ids, attention_mask, labels + ): + """ + Merge input_ids with audio features into final embeddings + + Args: + audio_features (`torch.Tensor` of shape `(num_audios, max_audio_tokens, embed_dim)`): + All audio vectors of all audios in the batch + num_audio_tokens (`torch.LongTensor` of shape `(num_audios)`): + The length of audio embeddings of each audio as stacked in `audio_features` + inputs_embeds (`torch.Tensor` of shape `(batch_size, sequence_length, embed_dim)`): + Token embeddings before merging with audio embeddings + input_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`): + Input_ids of tokens, possibly filled with audio token + attention_mask (`torch.LongTensor` of shape `(batch_size, sequence_length)`): + Mask to avoid performing attention on padding token indices. + labels (`torch.Tensor` of shape `(batch_size, sequence_length)`, *optional*) + labels need to be recalculated to support training (if provided) + Returns: + final_embedding, final_attention_mask, final_labels, position_ids, final_input_ids + + Explanation: + each audio has variable length embeddings, with length specified by num_audio_tokens + audio_features is concatenation of all audio embed vectors + task: fill each <|AUDIO|> with the correct number of audio embeddings + Example: + X (5 tokens), Y (3 tokens), Z (8 tokens) + X, Y are in the same sequence (in-context learning) + if right padding + input_ids: [ + a b c d e f X g h i j k Y l m + o p q r Z s t u v _ _ _ _ _ _ + ] + input_ids should be: [ + a b c d e f X X X X X g h i j k Y Y Y l m + o p q r Z Z Z Z Z Z Z Z s t u v _ _ _ _ _ + ] + labels should be: [ + a b c d e f _ _ _ _ _ g h i j k _ _ _ l m + o p q r _ _ _ _ _ _ _ _ s t u v _ _ _ _ _ + ] + elif left padding + input_ids: [ + a b c d e f X g h i j k Y l m + _ _ _ _ _ _ o p q r Z s t u v + ] + input_ids should be: [ + a b c d e f X X X X X g h i j k Y Y Y l m + _ _ _ _ _ o p q r Z Z Z Z Z Z Z Z s t u v + ] + labels should be: [ + a b c d e f _ _ _ _ _ g h i j k _ _ _ l m + _ _ _ _ _ o p q r _ _ _ _ _ _ _ _ s t u v + ] + Edge cases: + * If tokens are same but audio token sizes are different, then cannot infer left or right padding + ```python + url1 = "https://qianwen-res.oss-cn-beijing.aliyuncs.com/Qwen2-Audio/audio/glass-breaking-151256.mp3" + audio1, _ = librosa.load(BytesIO(urlopen(url1).read()), sr=processor.feature_extractor.sampling_rate) + url2 = "https://qianwen-res.oss-cn-beijing.aliyuncs.com/Qwen2-Audio/audio/f2641_0_throatclearing.wav" + audio2, _ = librosa.load(BytesIO(urlopen(url2).read()), sr=processor.feature_extractor.sampling_rate) + prompts = [ + "[INST] <|AUDIO|>\nWhat is that in this audio? [/INST]", + "[INST] <|AUDIO|>\nWhat is that in this audio? [/INST]", + ] + inputs = processor(text=prompts, audio=[audio1, audio2], return_tensors='pt', padding=True).to("cuda") + audio1 has 101 tokens, while audio2 has 72 tokens + ``` + + input_ids: [ + a b c d X g h + i j Y k l m n + ] + where X is 3 tokens while Y is 5, this mean after merge + if left-padding (batched generation) + input_ids should be: [ + _ _ a b c d X X X g h + i j Y Y Y Y Y k l m n + ] + elif (right padding) (training) + input_ids should be: [ + a b c d X X X g h _ _ + i j Y Y Y Y Y k l m n + ] + """ + num_audios, max_audio_tokens, embed_dim = audio_features.shape + audio_features_mask = torch.arange(max_audio_tokens).expand(num_audios, max_audio_tokens).to( + num_audio_tokens.device + ) < num_audio_tokens.unsqueeze(1) + masked_audio_features = audio_features[audio_features_mask].view(-1, embed_dim) + batch_size, sequence_length = input_ids.shape + _left_padding = torch.any(attention_mask[:, 0] == 0) + _right_padding = torch.any(attention_mask[:, -1] == 0) + + left_padding = True + if batch_size > 1: + if _left_padding and not _right_padding: + left_padding = True + elif not _left_padding and _right_padding: + left_padding = False + elif not _left_padding and not _right_padding: + # both side is 1, so cannot tell + left_padding = self.padding_side == "left" + else: + # invalid attention_mask + raise ValueError(f"both side of attention_mask has zero, invalid. {attention_mask}") + + # 1. Create a mask to know where special audio tokens are + special_audio_token_mask = input_ids == self.config.audio_token_id + num_special_audio_tokens = torch.sum(special_audio_token_mask, dim=-1) + + # In case the Audio model or the Language model has been offloaded to CPU, we need to manually + # set the corresponding tensors into their correct target device. + target_device = inputs_embeds.device + attention_mask = attention_mask.to(target_device) + input_ids = input_ids.to(target_device) + num_audio_tokens = num_audio_tokens.to(target_device) + batch_indices, non_audio_indices = torch.where( + (input_ids != self.config.audio_token_id) & (attention_mask == 1) + ) + + # 2. Compute the positions where text should be written + # Calculate new positions for text tokens in merged audio-text sequence. + # `special_audio_token_mask` identifies audio tokens. Each audio token will be replaced by `audio_feat_lengths - 1` text tokens. + # `torch.cumsum` computes how each audio token shifts subsequent text token positions. + token_placeholder_num = torch.zeros_like(input_ids) + token_placeholder_num[special_audio_token_mask] = num_audio_tokens.long() - 1 + token_placeholder_num = token_placeholder_num + 1 + new_token_positions = torch.cumsum(token_placeholder_num, -1) - 1 + max_token_num = token_placeholder_num.sum(-1).max() + nb_audio_pad = max_token_num - 1 - new_token_positions[:, -1] + if left_padding: + new_token_positions += nb_audio_pad[:, None] # offset for left padding + text_to_overwrite = new_token_positions[batch_indices, non_audio_indices] + batch_indices, non_audio_indices, text_to_overwrite = ( + batch_indices.to(target_device), + non_audio_indices.to(target_device), + text_to_overwrite.to(target_device), + ) + + # 3. Create the full embedding, already padded to the maximum position + final_embedding = torch.zeros( + batch_size, max_token_num, embed_dim, dtype=inputs_embeds.dtype, device=inputs_embeds.device + ) + final_attention_mask = torch.zeros( + batch_size, max_token_num, dtype=attention_mask.dtype, device=inputs_embeds.device + ) + final_input_ids = torch.full( + (batch_size, max_token_num), self.pad_token_id, dtype=input_ids.dtype, device=inputs_embeds.device + ) + + # 4. Fill the embeddings based on the mask. If we have ["hey" "", + unk_token: str = "", + _spm_precompiled_charsmap: str | None = None, + additional_special_tokens: list | None = None, + **kwargs, + ): + self._vocab = vocab or {} + self._merges = merges or [] + + self._tokenizer = Tokenizer( + BPE( + vocab=self._vocab, + merges=self._merges, + unk_token=str(unk_token), + fuse_unk=True, + byte_fallback=False, + dropout=None, + ) + ) + + if _spm_precompiled_charsmap is not None: + self._tokenizer.normalizer = normalizers.Sequence( + [ + normalizers.Precompiled(_spm_precompiled_charsmap), + normalizers.Replace(pattern=Regex(" {2,}"), content=" "), + ] + ) + + self._tokenizer.pre_tokenizer = pre_tokenizers.Metaspace(replacement="▁", prepend_scheme="always") + self._tokenizer.decoder = decoders.Metaspace(replacement="▁", prepend_scheme="always") + + super().__init__( + eos_token=eos_token, + unk_token=unk_token, + additional_special_tokens=additional_special_tokens or [], + **kwargs, + ) + + super()._post_init() + + +__all__ = ["ReformerTokenizer"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/regnet/__init__.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/regnet/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..a49c5ee7f2e424ea688f7e83a97dad4eb38cfc8b --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/regnet/__init__.py @@ -0,0 +1,27 @@ +# Copyright 2024 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from typing import TYPE_CHECKING + +from ...utils import _LazyModule +from ...utils.import_utils import define_import_structure + + +if TYPE_CHECKING: + from .configuration_regnet import * + from .modeling_regnet import * +else: + import sys + + _file = globals()["__file__"] + sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__) diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/regnet/configuration_regnet.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/regnet/configuration_regnet.py new file mode 100644 index 0000000000000000000000000000000000000000..406d2d0d8c394701043317d23850b0d858e1e6cb --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/regnet/configuration_regnet.py @@ -0,0 +1,93 @@ +# Copyright 2022 Meta Platforms, Inc. and The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""RegNet model configuration""" + +from ...configuration_utils import PreTrainedConfig +from ...utils import logging + + +logger = logging.get_logger(__name__) + + +class RegNetConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`RegNetModel`]. It is used to instantiate a RegNet + model according to the specified arguments, defining the model architecture. Instantiating a configuration with the + defaults will yield a similar configuration to that of the RegNet + [facebook/regnet-y-040](https://huggingface.co/facebook/regnet-y-040) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + num_channels (`int`, *optional*, defaults to 3): + The number of input channels. + embedding_size (`int`, *optional*, defaults to 64): + Dimensionality (hidden size) for the embedding layer. + hidden_sizes (`list[int]`, *optional*, defaults to `[256, 512, 1024, 2048]`): + Dimensionality (hidden size) at each stage. + depths (`list[int]`, *optional*, defaults to `[3, 4, 6, 3]`): + Depth (number of layers) for each stage. + layer_type (`str`, *optional*, defaults to `"y"`): + The layer to use, it can be either `"x" or `"y"`. An `x` layer is a ResNet's BottleNeck layer with + `reduction` fixed to `1`. While a `y` layer is a `x` but with squeeze and excitation. Please refer to the + paper for a detailed explanation of how these layers were constructed. + hidden_act (`str`, *optional*, defaults to `"relu"`): + The non-linear activation function in each block. If string, `"gelu"`, `"relu"`, `"selu"` and `"gelu_new"` + are supported. + downsample_in_first_stage (`bool`, *optional*, defaults to `False`): + If `True`, the first stage will downsample the inputs using a `stride` of 2. + + Example: + ```python + >>> from transformers import RegNetConfig, RegNetModel + + >>> # Initializing a RegNet regnet-y-40 style configuration + >>> configuration = RegNetConfig() + >>> # Initializing a model from the regnet-y-40 style configuration + >>> model = RegNetModel(configuration) + >>> # Accessing the model configuration + >>> configuration = model.config + ``` + """ + + model_type = "regnet" + layer_types = ["x", "y"] + + def __init__( + self, + num_channels=3, + embedding_size=32, + hidden_sizes=[128, 192, 512, 1088], + depths=[2, 6, 12, 2], + groups_width=64, + layer_type="y", + hidden_act="relu", + **kwargs, + ): + super().__init__(**kwargs) + if layer_type not in self.layer_types: + raise ValueError(f"layer_type={layer_type} is not one of {','.join(self.layer_types)}") + self.num_channels = num_channels + self.embedding_size = embedding_size + self.hidden_sizes = hidden_sizes + self.depths = depths + self.groups_width = groups_width + self.layer_type = layer_type + self.hidden_act = hidden_act + # always downsample in the first stage + self.downsample_in_first_stage = True + + +__all__ = ["RegNetConfig"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/regnet/modeling_regnet.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/regnet/modeling_regnet.py new file mode 100644 index 0000000000000000000000000000000000000000..f8db0b166b92c915cf93a44c803a284dd4c09703 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/regnet/modeling_regnet.py @@ -0,0 +1,384 @@ +# Copyright 2022 Meta Platforms, Inc. and The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""PyTorch RegNet model.""" + +import math + +import torch +from torch import Tensor, nn + +from ... import initialization as init +from ...activations import ACT2FN +from ...modeling_outputs import ( + BaseModelOutputWithNoAttention, + BaseModelOutputWithPoolingAndNoAttention, + ImageClassifierOutputWithNoAttention, +) +from ...modeling_utils import PreTrainedModel +from ...utils import auto_docstring, logging +from .configuration_regnet import RegNetConfig + + +logger = logging.get_logger(__name__) + + +class RegNetConvLayer(nn.Module): + def __init__( + self, + in_channels: int, + out_channels: int, + kernel_size: int = 3, + stride: int = 1, + groups: int = 1, + activation: str | None = "relu", + ): + super().__init__() + self.convolution = nn.Conv2d( + in_channels, + out_channels, + kernel_size=kernel_size, + stride=stride, + padding=kernel_size // 2, + groups=groups, + bias=False, + ) + self.normalization = nn.BatchNorm2d(out_channels) + self.activation = ACT2FN[activation] if activation is not None else nn.Identity() + + def forward(self, hidden_state): + hidden_state = self.convolution(hidden_state) + hidden_state = self.normalization(hidden_state) + hidden_state = self.activation(hidden_state) + return hidden_state + + +class RegNetEmbeddings(nn.Module): + """ + RegNet Embeddings (stem) composed of a single aggressive convolution. + """ + + def __init__(self, config: RegNetConfig): + super().__init__() + self.embedder = RegNetConvLayer( + config.num_channels, config.embedding_size, kernel_size=3, stride=2, activation=config.hidden_act + ) + self.num_channels = config.num_channels + + def forward(self, pixel_values): + num_channels = pixel_values.shape[1] + if num_channels != self.num_channels: + raise ValueError( + "Make sure that the channel dimension of the pixel values match with the one set in the configuration." + ) + hidden_state = self.embedder(pixel_values) + return hidden_state + + +# Copied from transformers.models.resnet.modeling_resnet.ResNetShortCut with ResNet->RegNet +class RegNetShortCut(nn.Module): + """ + RegNet shortcut, used to project the residual features to the correct size. If needed, it is also used to + downsample the input using `stride=2`. + """ + + def __init__(self, in_channels: int, out_channels: int, stride: int = 2): + super().__init__() + self.convolution = nn.Conv2d(in_channels, out_channels, kernel_size=1, stride=stride, bias=False) + self.normalization = nn.BatchNorm2d(out_channels) + + def forward(self, input: Tensor) -> Tensor: + hidden_state = self.convolution(input) + hidden_state = self.normalization(hidden_state) + return hidden_state + + +class RegNetSELayer(nn.Module): + """ + Squeeze and Excitation layer (SE) proposed in [Squeeze-and-Excitation Networks](https://huggingface.co/papers/1709.01507). + """ + + def __init__(self, in_channels: int, reduced_channels: int): + super().__init__() + + self.pooler = nn.AdaptiveAvgPool2d((1, 1)) + self.attention = nn.Sequential( + nn.Conv2d(in_channels, reduced_channels, kernel_size=1), + nn.ReLU(), + nn.Conv2d(reduced_channels, in_channels, kernel_size=1), + nn.Sigmoid(), + ) + + def forward(self, hidden_state): + # b c h w -> b c 1 1 + pooled = self.pooler(hidden_state) + attention = self.attention(pooled) + hidden_state = hidden_state * attention + return hidden_state + + +class RegNetXLayer(nn.Module): + """ + RegNet's layer composed by three `3x3` convolutions, same as a ResNet bottleneck layer with reduction = 1. + """ + + def __init__(self, config: RegNetConfig, in_channels: int, out_channels: int, stride: int = 1): + super().__init__() + should_apply_shortcut = in_channels != out_channels or stride != 1 + groups = max(1, out_channels // config.groups_width) + self.shortcut = ( + RegNetShortCut(in_channels, out_channels, stride=stride) if should_apply_shortcut else nn.Identity() + ) + self.layer = nn.Sequential( + RegNetConvLayer(in_channels, out_channels, kernel_size=1, activation=config.hidden_act), + RegNetConvLayer(out_channels, out_channels, stride=stride, groups=groups, activation=config.hidden_act), + RegNetConvLayer(out_channels, out_channels, kernel_size=1, activation=None), + ) + self.activation = ACT2FN[config.hidden_act] + + def forward(self, hidden_state): + residual = hidden_state + hidden_state = self.layer(hidden_state) + residual = self.shortcut(residual) + hidden_state += residual + hidden_state = self.activation(hidden_state) + return hidden_state + + +class RegNetYLayer(nn.Module): + """ + RegNet's Y layer: an X layer with Squeeze and Excitation. + """ + + def __init__(self, config: RegNetConfig, in_channels: int, out_channels: int, stride: int = 1): + super().__init__() + should_apply_shortcut = in_channels != out_channels or stride != 1 + groups = max(1, out_channels // config.groups_width) + self.shortcut = ( + RegNetShortCut(in_channels, out_channels, stride=stride) if should_apply_shortcut else nn.Identity() + ) + self.layer = nn.Sequential( + RegNetConvLayer(in_channels, out_channels, kernel_size=1, activation=config.hidden_act), + RegNetConvLayer(out_channels, out_channels, stride=stride, groups=groups, activation=config.hidden_act), + RegNetSELayer(out_channels, reduced_channels=int(round(in_channels / 4))), + RegNetConvLayer(out_channels, out_channels, kernel_size=1, activation=None), + ) + self.activation = ACT2FN[config.hidden_act] + + def forward(self, hidden_state): + residual = hidden_state + hidden_state = self.layer(hidden_state) + residual = self.shortcut(residual) + hidden_state += residual + hidden_state = self.activation(hidden_state) + return hidden_state + + +class RegNetStage(nn.Module): + """ + A RegNet stage composed by stacked layers. + """ + + def __init__( + self, + config: RegNetConfig, + in_channels: int, + out_channels: int, + stride: int = 2, + depth: int = 2, + ): + super().__init__() + + layer = RegNetXLayer if config.layer_type == "x" else RegNetYLayer + + self.layers = nn.Sequential( + # downsampling is done in the first layer with stride of 2 + layer( + config, + in_channels, + out_channels, + stride=stride, + ), + *[layer(config, out_channels, out_channels) for _ in range(depth - 1)], + ) + + def forward(self, hidden_state): + hidden_state = self.layers(hidden_state) + return hidden_state + + +class RegNetEncoder(nn.Module): + def __init__(self, config: RegNetConfig): + super().__init__() + self.stages = nn.ModuleList([]) + # based on `downsample_in_first_stage`, the first layer of the first stage may or may not downsample the input + self.stages.append( + RegNetStage( + config, + config.embedding_size, + config.hidden_sizes[0], + stride=2 if config.downsample_in_first_stage else 1, + depth=config.depths[0], + ) + ) + in_out_channels = zip(config.hidden_sizes, config.hidden_sizes[1:]) + for (in_channels, out_channels), depth in zip(in_out_channels, config.depths[1:]): + self.stages.append(RegNetStage(config, in_channels, out_channels, depth=depth)) + + def forward( + self, hidden_state: Tensor, output_hidden_states: bool = False, return_dict: bool = True + ) -> BaseModelOutputWithNoAttention: + hidden_states = () if output_hidden_states else None + + for stage_module in self.stages: + if output_hidden_states: + hidden_states = hidden_states + (hidden_state,) + + hidden_state = stage_module(hidden_state) + + if output_hidden_states: + hidden_states = hidden_states + (hidden_state,) + + if not return_dict: + return tuple(v for v in [hidden_state, hidden_states] if v is not None) + + return BaseModelOutputWithNoAttention(last_hidden_state=hidden_state, hidden_states=hidden_states) + + +@auto_docstring +class RegNetPreTrainedModel(PreTrainedModel): + config: RegNetConfig + base_model_prefix = "regnet" + main_input_name = "pixel_values" + _no_split_modules = ["RegNetYLayer"] + + @torch.no_grad() + def _init_weights(self, module): + if isinstance(module, nn.Conv2d): + init.kaiming_normal_(module.weight, mode="fan_out", nonlinearity="relu") + # copied from the `reset_parameters` method of `class Linear(Module)` in `torch`. + elif isinstance(module, nn.Linear): + init.kaiming_uniform_(module.weight, a=math.sqrt(5)) + if module.bias is not None: + fan_in, _ = torch.nn.init._calculate_fan_in_and_fan_out(module.weight) + bound = 1 / math.sqrt(fan_in) if fan_in > 0 else 0 + init.uniform_(module.bias, -bound, bound) + elif isinstance(module, (nn.BatchNorm2d, nn.GroupNorm)): + init.constant_(module.weight, 1) + init.constant_(module.bias, 0) + if getattr(module, "running_mean", None) is not None: + init.zeros_(module.running_mean) + init.ones_(module.running_var) + init.zeros_(module.num_batches_tracked) + + +@auto_docstring +# Copied from transformers.models.resnet.modeling_resnet.ResNetModel with RESNET->REGNET,ResNet->RegNet +class RegNetModel(RegNetPreTrainedModel): + def __init__(self, config): + super().__init__(config) + self.config = config + self.embedder = RegNetEmbeddings(config) + self.encoder = RegNetEncoder(config) + self.pooler = nn.AdaptiveAvgPool2d((1, 1)) + # Initialize weights and apply final processing + self.post_init() + + @auto_docstring + def forward( + self, + pixel_values: Tensor, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + **kwargs, + ) -> BaseModelOutputWithPoolingAndNoAttention: + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + embedding_output = self.embedder(pixel_values) + + encoder_outputs = self.encoder( + embedding_output, output_hidden_states=output_hidden_states, return_dict=return_dict + ) + + last_hidden_state = encoder_outputs[0] + + pooled_output = self.pooler(last_hidden_state) + + if not return_dict: + return (last_hidden_state, pooled_output) + encoder_outputs[1:] + + return BaseModelOutputWithPoolingAndNoAttention( + last_hidden_state=last_hidden_state, + pooler_output=pooled_output, + hidden_states=encoder_outputs.hidden_states, + ) + + +@auto_docstring( + custom_intro=""" + RegNet Model with an image classification head on top (a linear layer on top of the pooled features), e.g. for + ImageNet. + """ +) +# Copied from transformers.models.resnet.modeling_resnet.ResNetForImageClassification with RESNET->REGNET,ResNet->RegNet,resnet->regnet +class RegNetForImageClassification(RegNetPreTrainedModel): + def __init__(self, config): + super().__init__(config) + self.num_labels = config.num_labels + self.regnet = RegNetModel(config) + # classification head + self.classifier = nn.Sequential( + nn.Flatten(), + nn.Linear(config.hidden_sizes[-1], config.num_labels) if config.num_labels > 0 else nn.Identity(), + ) + # initialize weights and apply final processing + self.post_init() + + @auto_docstring + def forward( + self, + pixel_values: torch.FloatTensor | None = None, + labels: torch.LongTensor | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + **kwargs, + ) -> ImageClassifierOutputWithNoAttention: + r""" + labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*): + Labels for computing the image classification/regression loss. Indices should be in `[0, ..., + config.num_labels - 1]`. If `config.num_labels > 1` a classification loss is computed (Cross-Entropy). + """ + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + outputs = self.regnet(pixel_values, output_hidden_states=output_hidden_states, return_dict=return_dict) + + pooled_output = outputs.pooler_output if return_dict else outputs[1] + + logits = self.classifier(pooled_output) + + loss = None + + if labels is not None: + loss = self.loss_function(labels, logits, self.config) + + if not return_dict: + output = (logits,) + outputs[2:] + return (loss,) + output if loss is not None else output + + return ImageClassifierOutputWithNoAttention(loss=loss, logits=logits, hidden_states=outputs.hidden_states) + + +__all__ = ["RegNetForImageClassification", "RegNetModel", "RegNetPreTrainedModel"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/rembert/__init__.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/rembert/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..371d23ef13a7ca20e9f3b6afa75cadad488e1fea --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/rembert/__init__.py @@ -0,0 +1,28 @@ +# Copyright 2024 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from typing import TYPE_CHECKING + +from ...utils import _LazyModule +from ...utils.import_utils import define_import_structure + + +if TYPE_CHECKING: + from .configuration_rembert import * + from .modeling_rembert import * + from .tokenization_rembert import * +else: + import sys + + _file = globals()["__file__"] + sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__) diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/rembert/configuration_rembert.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/rembert/configuration_rembert.py new file mode 100644 index 0000000000000000000000000000000000000000..f32e12e60059bcf03f369225327db8fe8eb19c10 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/rembert/configuration_rembert.py @@ -0,0 +1,144 @@ +# Copyright The HuggingFace Team and The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""RemBERT model configuration""" + +from ...configuration_utils import PreTrainedConfig +from ...utils import logging + + +logger = logging.get_logger(__name__) + + +class RemBertConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`RemBertModel`]. It is used to instantiate an + RemBERT model according to the specified arguments, defining the model architecture. Instantiating a configuration + with the defaults will yield a similar configuration to that of the RemBERT + [google/rembert](https://huggingface.co/google/rembert) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + + Args: + vocab_size (`int`, *optional*, defaults to 250300): + Vocabulary size of the RemBERT model. Defines the number of different tokens that can be represented by the + `inputs_ids` passed when calling [`RemBertModel`]. Vocabulary size of the model. + Defines the different tokens that can be represented by the *inputs_ids* passed to the forward method of + [`RemBertModel`]. + hidden_size (`int`, *optional*, defaults to 1152): + Dimensionality of the encoder layers and the pooler layer. + num_hidden_layers (`int`, *optional*, defaults to 32): + Number of hidden layers in the Transformer encoder. + num_attention_heads (`int`, *optional*, defaults to 18): + Number of attention heads for each attention layer in the Transformer encoder. + input_embedding_size (`int`, *optional*, defaults to 256): + Dimensionality of the input embeddings. + output_embedding_size (`int`, *optional*, defaults to 1664): + Dimensionality of the output embeddings. + intermediate_size (`int`, *optional*, defaults to 4608): + Dimensionality of the "intermediate" (i.e., feed-forward) layer in the Transformer encoder. + hidden_act (`str` or `function`, *optional*, defaults to `"gelu"`): + The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`, + `"relu"`, `"selu"` and `"gelu_new"` are supported. + hidden_dropout_prob (`float`, *optional*, defaults to 0): + The dropout probability for all fully connected layers in the embeddings, encoder, and pooler. + attention_probs_dropout_prob (`float`, *optional*, defaults to 0): + The dropout ratio for the attention probabilities. + classifier_dropout_prob (`float`, *optional*, defaults to 0.1): + The dropout ratio for the classifier layer when fine-tuning. + max_position_embeddings (`int`, *optional*, defaults to 512): + The maximum sequence length that this model might ever be used with. Typically set this to something large + just in case (e.g., 512 or 1024 or 2048). + type_vocab_size (`int`, *optional*, defaults to 2): + The vocabulary size of the `token_type_ids` passed when calling [`RemBertModel`]. + initializer_range (`float`, *optional*, defaults to 0.02): + The standard deviation of the truncated_normal_initializer for initializing all weight matrices. + layer_norm_eps (`float`, *optional*, defaults to 1e-12): + The epsilon used by the layer normalization layers. + is_decoder (`bool`, *optional*, defaults to `False`): + Whether the model is used as a decoder or not. If `False`, the model is used as an encoder. + use_cache (`bool`, *optional*, defaults to `True`): + Whether or not the model should return the last key/values attentions (not used by all models). Only + relevant if `config.is_decoder=True`. + + Example: + + ```python + >>> from transformers import RemBertModel, RemBertConfig + + >>> # Initializing a RemBERT rembert style configuration + >>> configuration = RemBertConfig() + + >>> # Initializing a model from the rembert style configuration + >>> model = RemBertModel(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "rembert" + + def __init__( + self, + vocab_size=250300, + hidden_size=1152, + num_hidden_layers=32, + num_attention_heads=18, + input_embedding_size=256, + output_embedding_size=1664, + intermediate_size=4608, + hidden_act="gelu", + hidden_dropout_prob=0.0, + attention_probs_dropout_prob=0.0, + classifier_dropout_prob=0.1, + max_position_embeddings=512, + type_vocab_size=2, + initializer_range=0.02, + layer_norm_eps=1e-12, + use_cache=True, + pad_token_id=0, + bos_token_id=312, + eos_token_id=313, + is_decoder=False, + add_cross_attention=False, + **kwargs, + ): + super().__init__(**kwargs) + self.pad_token_id = pad_token_id + self.bos_token_id = bos_token_id + self.eos_token_id = eos_token_id + + self.is_decoder = is_decoder + self.add_cross_attention = add_cross_attention + self.vocab_size = vocab_size + self.input_embedding_size = input_embedding_size + self.output_embedding_size = output_embedding_size + self.max_position_embeddings = max_position_embeddings + self.hidden_size = hidden_size + self.num_hidden_layers = num_hidden_layers + self.num_attention_heads = num_attention_heads + self.intermediate_size = intermediate_size + self.hidden_act = hidden_act + self.hidden_dropout_prob = hidden_dropout_prob + self.attention_probs_dropout_prob = attention_probs_dropout_prob + self.classifier_dropout_prob = classifier_dropout_prob + self.initializer_range = initializer_range + self.type_vocab_size = type_vocab_size + self.layer_norm_eps = layer_norm_eps + self.use_cache = use_cache + self.tie_word_embeddings = False + + +__all__ = ["RemBertConfig"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/rembert/modeling_rembert.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/rembert/modeling_rembert.py new file mode 100644 index 0000000000000000000000000000000000000000..666aa080cc22ef5409e9523ef42600ca2b6b95ce --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/rembert/modeling_rembert.py @@ -0,0 +1,1161 @@ +# Copyright 2021 The HuggingFace Team The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""PyTorch RemBERT model.""" + +import math + +import torch +from torch import nn +from torch.nn import BCEWithLogitsLoss, CrossEntropyLoss, MSELoss + +from ... import initialization as init +from ...activations import ACT2FN +from ...cache_utils import Cache, DynamicCache, EncoderDecoderCache +from ...generation import GenerationMixin +from ...modeling_layers import GradientCheckpointingLayer +from ...modeling_outputs import ( + BaseModelOutputWithPastAndCrossAttentions, + BaseModelOutputWithPoolingAndCrossAttentions, + CausalLMOutputWithCrossAttentions, + MaskedLMOutput, + MultipleChoiceModelOutput, + QuestionAnsweringModelOutput, + SequenceClassifierOutput, + TokenClassifierOutput, +) +from ...modeling_utils import PreTrainedModel +from ...pytorch_utils import apply_chunking_to_forward +from ...utils import auto_docstring, logging +from .configuration_rembert import RemBertConfig + + +logger = logging.get_logger(__name__) + + +class RemBertEmbeddings(nn.Module): + """Construct the embeddings from word, position and token_type embeddings.""" + + def __init__(self, config): + super().__init__() + self.word_embeddings = nn.Embedding( + config.vocab_size, config.input_embedding_size, padding_idx=config.pad_token_id + ) + self.position_embeddings = nn.Embedding(config.max_position_embeddings, config.input_embedding_size) + self.token_type_embeddings = nn.Embedding(config.type_vocab_size, config.input_embedding_size) + + self.LayerNorm = nn.LayerNorm(config.input_embedding_size, eps=config.layer_norm_eps) + self.dropout = nn.Dropout(config.hidden_dropout_prob) + + # position_ids (1, len position emb) is contiguous in memory and exported when serialized + self.register_buffer( + "position_ids", torch.arange(config.max_position_embeddings).expand((1, -1)), persistent=False + ) + + def forward( + self, + input_ids: torch.LongTensor | None = None, + token_type_ids: torch.LongTensor | None = None, + position_ids: torch.LongTensor | None = None, + inputs_embeds: torch.FloatTensor | None = None, + past_key_values_length: int = 0, + ) -> torch.Tensor: + if input_ids is not None: + input_shape = input_ids.size() + else: + input_shape = inputs_embeds.size()[:-1] + + seq_length = input_shape[1] + + if position_ids is None: + position_ids = self.position_ids[:, past_key_values_length : seq_length + past_key_values_length] + + if token_type_ids is None: + token_type_ids = torch.zeros(input_shape, dtype=torch.long, device=self.position_ids.device) + + if inputs_embeds is None: + inputs_embeds = self.word_embeddings(input_ids) + token_type_embeddings = self.token_type_embeddings(token_type_ids) + + embeddings = inputs_embeds + token_type_embeddings + position_embeddings = self.position_embeddings(position_ids) + embeddings += position_embeddings + embeddings = self.LayerNorm(embeddings) + embeddings = self.dropout(embeddings) + return embeddings + + +# Copied from transformers.models.bert.modeling_bert.BertPooler with Bert->RemBert +class RemBertPooler(nn.Module): + def __init__(self, config): + super().__init__() + self.dense = nn.Linear(config.hidden_size, config.hidden_size) + self.activation = nn.Tanh() + + def forward(self, hidden_states: torch.Tensor) -> torch.Tensor: + # We "pool" the model by simply taking the hidden state corresponding + # to the first token. + first_token_tensor = hidden_states[:, 0] + pooled_output = self.dense(first_token_tensor) + pooled_output = self.activation(pooled_output) + return pooled_output + + +class RemBertSelfAttention(nn.Module): + def __init__(self, config, layer_idx=None): + super().__init__() + if config.hidden_size % config.num_attention_heads != 0 and not hasattr(config, "embedding_size"): + raise ValueError( + f"The hidden size ({config.hidden_size}) is not a multiple of the number of attention " + f"heads ({config.num_attention_heads})" + ) + + self.num_attention_heads = config.num_attention_heads + self.attention_head_size = int(config.hidden_size / config.num_attention_heads) + self.all_head_size = self.num_attention_heads * self.attention_head_size + + self.query = nn.Linear(config.hidden_size, self.all_head_size) + self.key = nn.Linear(config.hidden_size, self.all_head_size) + self.value = nn.Linear(config.hidden_size, self.all_head_size) + + self.dropout = nn.Dropout(config.attention_probs_dropout_prob) + + self.is_decoder = config.is_decoder + self.layer_idx = layer_idx + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.FloatTensor | None = None, + encoder_hidden_states: torch.FloatTensor | None = None, + past_key_values: Cache | None = None, + output_attentions: bool = False, + cache_position: torch.Tensor | None = None, + ) -> tuple: + batch_size, seq_length, _ = hidden_states.shape + query_layer = ( + self.query(hidden_states) + .view(batch_size, -1, self.num_attention_heads, self.attention_head_size) + .transpose(1, 2) + ) + + is_updated = False + is_cross_attention = encoder_hidden_states is not None + if past_key_values is not None: + if isinstance(past_key_values, EncoderDecoderCache): + is_updated = past_key_values.is_updated.get(self.layer_idx) + if is_cross_attention: + # after the first generated id, we can subsequently re-use all key/value_layer from cache + curr_past_key_values = past_key_values.cross_attention_cache + else: + curr_past_key_values = past_key_values.self_attention_cache + else: + curr_past_key_values = past_key_values + + current_states = encoder_hidden_states if is_cross_attention else hidden_states + if is_cross_attention and past_key_values is not None and is_updated: + # reuse k,v, cross_attentions + key_layer = curr_past_key_values.layers[self.layer_idx].keys + value_layer = curr_past_key_values.layers[self.layer_idx].values + else: + key_layer = ( + self.key(current_states) + .view(batch_size, -1, self.num_attention_heads, self.attention_head_size) + .transpose(1, 2) + ) + value_layer = ( + self.value(current_states) + .view(batch_size, -1, self.num_attention_heads, self.attention_head_size) + .transpose(1, 2) + ) + + if past_key_values is not None: + # save all key/value_layer to cache to be re-used for fast auto-regressive generation + cache_position = cache_position if not is_cross_attention else None + key_layer, value_layer = curr_past_key_values.update( + key_layer, value_layer, self.layer_idx, {"cache_position": cache_position} + ) + # set flag that curr layer for cross-attn is already updated so we can re-use in subsequent calls + if is_cross_attention and isinstance(past_key_values, EncoderDecoderCache): + past_key_values.is_updated[self.layer_idx] = True + + # Take the dot product between "query" and "key" to get the raw attention scores. + attention_scores = torch.matmul(query_layer, key_layer.transpose(-1, -2)) + + attention_scores = attention_scores / math.sqrt(self.attention_head_size) + if attention_mask is not None: + # Apply the attention mask is (precomputed for all layers in RemBertModel forward() function) + attention_scores = attention_scores + attention_mask + + # Normalize the attention scores to probabilities. + attention_probs = nn.functional.softmax(attention_scores, dim=-1) + + # This is actually dropping out entire tokens to attend to, which might + # seem a bit unusual, but is taken from the original Transformer paper. + attention_probs = self.dropout(attention_probs) + + context_layer = torch.matmul(attention_probs, value_layer) + + context_layer = context_layer.permute(0, 2, 1, 3).contiguous() + new_context_layer_shape = context_layer.size()[:-2] + (self.all_head_size,) + context_layer = context_layer.view(*new_context_layer_shape) + + return context_layer, attention_probs + + +# Copied from transformers.models.bert.modeling_bert.BertSelfOutput with Bert->RemBert +class RemBertSelfOutput(nn.Module): + def __init__(self, config): + super().__init__() + self.dense = nn.Linear(config.hidden_size, config.hidden_size) + self.LayerNorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps) + self.dropout = nn.Dropout(config.hidden_dropout_prob) + + def forward(self, hidden_states: torch.Tensor, input_tensor: torch.Tensor) -> torch.Tensor: + hidden_states = self.dense(hidden_states) + hidden_states = self.dropout(hidden_states) + hidden_states = self.LayerNorm(hidden_states + input_tensor) + return hidden_states + + +class RemBertAttention(nn.Module): + def __init__(self, config, layer_idx=None): + super().__init__() + self.self = RemBertSelfAttention(config, layer_idx=layer_idx) + self.output = RemBertSelfOutput(config) + + # copied from transformers.models.bert.modeling_bert.BertAttention.forward + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.FloatTensor | None = None, + encoder_hidden_states: torch.FloatTensor | None = None, + past_key_values: Cache | None = None, + output_attentions: bool | None = False, + cache_position: torch.Tensor | None = None, + ) -> tuple[torch.Tensor]: + self_outputs = self.self( + hidden_states, + attention_mask=attention_mask, + encoder_hidden_states=encoder_hidden_states, + past_key_values=past_key_values, + output_attentions=output_attentions, + cache_position=cache_position, + ) + attention_output = self.output(self_outputs[0], hidden_states) + outputs = (attention_output,) + self_outputs[1:] # add attentions if we output them + return outputs + + +# Copied from transformers.models.bert.modeling_bert.BertIntermediate with Bert->RemBert +class RemBertIntermediate(nn.Module): + def __init__(self, config): + super().__init__() + self.dense = nn.Linear(config.hidden_size, config.intermediate_size) + if isinstance(config.hidden_act, str): + self.intermediate_act_fn = ACT2FN[config.hidden_act] + else: + self.intermediate_act_fn = config.hidden_act + + def forward(self, hidden_states: torch.Tensor) -> torch.Tensor: + hidden_states = self.dense(hidden_states) + hidden_states = self.intermediate_act_fn(hidden_states) + return hidden_states + + +# Copied from transformers.models.bert.modeling_bert.BertOutput with Bert->RemBert +class RemBertOutput(nn.Module): + def __init__(self, config): + super().__init__() + self.dense = nn.Linear(config.intermediate_size, config.hidden_size) + self.LayerNorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps) + self.dropout = nn.Dropout(config.hidden_dropout_prob) + + def forward(self, hidden_states: torch.Tensor, input_tensor: torch.Tensor) -> torch.Tensor: + hidden_states = self.dense(hidden_states) + hidden_states = self.dropout(hidden_states) + hidden_states = self.LayerNorm(hidden_states + input_tensor) + return hidden_states + + +class RemBertLayer(GradientCheckpointingLayer): + def __init__(self, config, layer_idx=None): + super().__init__() + self.chunk_size_feed_forward = config.chunk_size_feed_forward + self.seq_len_dim = 1 + self.attention = RemBertAttention(config, layer_idx) + self.is_decoder = config.is_decoder + self.add_cross_attention = config.add_cross_attention + if self.add_cross_attention: + if not self.is_decoder: + raise ValueError(f"{self} should be used as a decoder model if cross attention is added") + self.crossattention = RemBertAttention(config, layer_idx=layer_idx) + self.intermediate = RemBertIntermediate(config) + self.output = RemBertOutput(config) + + # copied from transformers.models.bert.modeling_bert.BertLayer.forward + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.FloatTensor | None = None, + encoder_hidden_states: torch.FloatTensor | None = None, + encoder_attention_mask: torch.FloatTensor | None = None, + past_key_values: Cache | None = None, + output_attentions: bool | None = False, + cache_position: torch.Tensor | None = None, + ) -> tuple[torch.Tensor]: + self_attention_outputs = self.attention( + hidden_states, + attention_mask=attention_mask, + output_attentions=output_attentions, + past_key_values=past_key_values, + cache_position=cache_position, + ) + attention_output = self_attention_outputs[0] + outputs = self_attention_outputs[1:] # add self attentions if we output attention weights + + if self.is_decoder and encoder_hidden_states is not None: + if not hasattr(self, "crossattention"): + raise ValueError( + f"If `encoder_hidden_states` are passed, {self} has to be instantiated with cross-attention layers" + " by setting `config.add_cross_attention=True`" + ) + + cross_attention_outputs = self.crossattention( + attention_output, + attention_mask=encoder_attention_mask, + encoder_hidden_states=encoder_hidden_states, + past_key_values=past_key_values, + output_attentions=output_attentions, + cache_position=cache_position, + ) + attention_output = cross_attention_outputs[0] + outputs = outputs + cross_attention_outputs[1:] # add cross attentions if we output attention weights + + layer_output = apply_chunking_to_forward( + self.feed_forward_chunk, self.chunk_size_feed_forward, self.seq_len_dim, attention_output + ) + outputs = (layer_output,) + outputs + + return outputs + + # Copied from transformers.models.bert.modeling_bert.BertLayer.feed_forward_chunk + def feed_forward_chunk(self, attention_output): + intermediate_output = self.intermediate(attention_output) + layer_output = self.output(intermediate_output, attention_output) + return layer_output + + +class RemBertEncoder(nn.Module): + def __init__(self, config): + super().__init__() + self.config = config + + self.embedding_hidden_mapping_in = nn.Linear(config.input_embedding_size, config.hidden_size) + self.layer = nn.ModuleList([RemBertLayer(config, layer_idx=i) for i in range(config.num_hidden_layers)]) + self.gradient_checkpointing = False + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.FloatTensor | None = None, + encoder_hidden_states: torch.FloatTensor | None = None, + encoder_attention_mask: torch.FloatTensor | None = None, + past_key_values: Cache | None = None, + use_cache: bool | None = None, + output_attentions: bool = False, + output_hidden_states: bool = False, + return_dict: bool = True, + cache_position: torch.Tensor | None = None, + ) -> tuple | BaseModelOutputWithPastAndCrossAttentions: + if self.gradient_checkpointing and self.training: + if use_cache: + logger.warning_once( + "`use_cache=True` is incompatible with gradient checkpointing. Setting `use_cache=False`..." + ) + use_cache = False + + if use_cache and past_key_values is None: + past_key_values = EncoderDecoderCache(DynamicCache(config=self.config), DynamicCache(config=self.config)) + + hidden_states = self.embedding_hidden_mapping_in(hidden_states) + all_hidden_states = () if output_hidden_states else None + all_self_attentions = () if output_attentions else None + all_cross_attentions = () if output_attentions and self.config.add_cross_attention else None + + for i, layer_module in enumerate(self.layer): + if output_hidden_states: + all_hidden_states = all_hidden_states + (hidden_states,) + + layer_outputs = layer_module( + hidden_states, + attention_mask, + encoder_hidden_states, + encoder_attention_mask, + past_key_values, + output_attentions, + ) + + hidden_states = layer_outputs[0] + if output_attentions: + all_self_attentions = all_self_attentions + (layer_outputs[1],) + if self.config.add_cross_attention: + all_cross_attentions = all_cross_attentions + (layer_outputs[2],) + + if output_hidden_states: + all_hidden_states = all_hidden_states + (hidden_states,) + + if not return_dict: + return tuple( + v + for v in [ + hidden_states, + past_key_values, + all_hidden_states, + all_self_attentions, + all_cross_attentions, + ] + if v is not None + ) + return BaseModelOutputWithPastAndCrossAttentions( + last_hidden_state=hidden_states, + past_key_values=past_key_values, + hidden_states=all_hidden_states, + attentions=all_self_attentions, + cross_attentions=all_cross_attentions, + ) + + +# Copied from transformers.models.bert.modeling_bert.BertPredictionHeadTransform with Bert->RemBert +class RemBertPredictionHeadTransform(nn.Module): + def __init__(self, config): + super().__init__() + self.dense = nn.Linear(config.hidden_size, config.hidden_size) + if isinstance(config.hidden_act, str): + self.transform_act_fn = ACT2FN[config.hidden_act] + else: + self.transform_act_fn = config.hidden_act + self.LayerNorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps) + + def forward(self, hidden_states: torch.Tensor) -> torch.Tensor: + hidden_states = self.dense(hidden_states) + hidden_states = self.transform_act_fn(hidden_states) + hidden_states = self.LayerNorm(hidden_states) + return hidden_states + + +class RemBertLMPredictionHead(nn.Module): + def __init__(self, config): + super().__init__() + self.dense = nn.Linear(config.hidden_size, config.output_embedding_size) + self.decoder = nn.Linear(config.output_embedding_size, config.vocab_size) + self.activation = ACT2FN[config.hidden_act] + self.LayerNorm = nn.LayerNorm(config.output_embedding_size, eps=config.layer_norm_eps) + + def forward(self, hidden_states: torch.Tensor) -> torch.Tensor: + hidden_states = self.dense(hidden_states) + hidden_states = self.activation(hidden_states) + hidden_states = self.LayerNorm(hidden_states) + hidden_states = self.decoder(hidden_states) + return hidden_states + + +# Copied from transformers.models.bert.modeling_bert.BertOnlyMLMHead with Bert->RemBert +class RemBertOnlyMLMHead(nn.Module): + def __init__(self, config): + super().__init__() + self.predictions = RemBertLMPredictionHead(config) + + def forward(self, sequence_output: torch.Tensor) -> torch.Tensor: + prediction_scores = self.predictions(sequence_output) + return prediction_scores + + +@auto_docstring +class RemBertPreTrainedModel(PreTrainedModel): + config: RemBertConfig + base_model_prefix = "rembert" + supports_gradient_checkpointing = True + + def _init_weights(self, module): + super()._init_weights(module) + if isinstance(module, RemBertEmbeddings): + init.copy_(module.position_ids, torch.arange(module.position_ids.shape[-1]).expand((1, -1))) + + +@auto_docstring( + custom_intro=""" + The model can behave as an encoder (with only self-attention) as well as a decoder, in which case a layer of + cross-attention is added between the self-attention layers, following the architecture described in [Attention is + all you need](https://huggingface.co/papers/1706.03762) by Ashish Vaswani, Noam Shazeer, Niki Parmar, Jakob Uszkoreit, + Llion Jones, Aidan N. Gomez, Lukasz Kaiser and Illia Polosukhin. + + To behave as an decoder the model needs to be initialized with the `is_decoder` argument of the configuration set + to `True`. To be used in a Seq2Seq model, the model needs to initialized with both `is_decoder` argument and + `add_cross_attention` set to `True`; an `encoder_hidden_states` is then expected as an input to the forward pass. + """ +) +class RemBertModel(RemBertPreTrainedModel): + def __init__(self, config, add_pooling_layer=True): + r""" + add_pooling_layer (bool, *optional*, defaults to `True`): + Whether to add a pooling layer + """ + super().__init__(config) + self.config = config + + self.embeddings = RemBertEmbeddings(config) + self.encoder = RemBertEncoder(config) + + self.pooler = RemBertPooler(config) if add_pooling_layer else None + + # Initialize weights and apply final processing + self.post_init() + + def get_input_embeddings(self): + return self.embeddings.word_embeddings + + def set_input_embeddings(self, value): + self.embeddings.word_embeddings = value + + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.LongTensor | None = None, + token_type_ids: torch.LongTensor | None = None, + position_ids: torch.LongTensor | None = None, + inputs_embeds: torch.FloatTensor | None = None, + encoder_hidden_states: torch.FloatTensor | None = None, + encoder_attention_mask: torch.FloatTensor | None = None, + past_key_values: Cache | None = None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + cache_position: torch.Tensor | None = None, + **kwargs, + ) -> tuple | BaseModelOutputWithPoolingAndCrossAttentions: + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + if self.config.is_decoder: + use_cache = use_cache if use_cache is not None else self.config.use_cache + else: + use_cache = False + + if input_ids is not None and inputs_embeds is not None: + raise ValueError("You cannot specify both input_ids and inputs_embeds at the same time") + elif input_ids is not None: + self.warn_if_padding_and_no_attention_mask(input_ids, attention_mask) + input_shape = input_ids.size() + elif inputs_embeds is not None: + input_shape = inputs_embeds.size()[:-1] + else: + raise ValueError("You have to specify either input_ids or inputs_embeds") + + batch_size, seq_length = input_shape + device = input_ids.device if input_ids is not None else inputs_embeds.device + + past_key_values_length = 0 if past_key_values is None else past_key_values.get_seq_length() + + if attention_mask is None: + attention_mask = torch.ones(((batch_size, seq_length + past_key_values_length)), device=device) + if token_type_ids is None: + token_type_ids = torch.zeros(input_shape, dtype=torch.long, device=device) + + # We can provide a self-attention mask of dimensions [batch_size, from_seq_length, to_seq_length] + # ourselves in which case we just need to make it broadcastable to all heads. + extended_attention_mask: torch.Tensor = self.get_extended_attention_mask(attention_mask, input_shape) + + # If a 2D or 3D attention mask is provided for the cross-attention + # we need to make broadcastable to [batch_size, num_heads, seq_length, seq_length] + if self.config.is_decoder and encoder_hidden_states is not None: + encoder_batch_size, encoder_sequence_length, _ = encoder_hidden_states.size() + encoder_hidden_shape = (encoder_batch_size, encoder_sequence_length) + if encoder_attention_mask is None: + encoder_attention_mask = torch.ones(encoder_hidden_shape, device=device) + encoder_extended_attention_mask = self.invert_attention_mask(encoder_attention_mask) + else: + encoder_extended_attention_mask = None + + embedding_output = self.embeddings( + input_ids=input_ids, + position_ids=position_ids, + token_type_ids=token_type_ids, + inputs_embeds=inputs_embeds, + past_key_values_length=past_key_values_length, + ) + encoder_outputs = self.encoder( + embedding_output, + attention_mask=extended_attention_mask, + encoder_hidden_states=encoder_hidden_states, + encoder_attention_mask=encoder_extended_attention_mask, + past_key_values=past_key_values, + use_cache=use_cache, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + cache_position=cache_position, + ) + sequence_output = encoder_outputs[0] + pooled_output = self.pooler(sequence_output) if self.pooler is not None else None + + if not return_dict: + return (sequence_output, pooled_output) + encoder_outputs[1:] + + return BaseModelOutputWithPoolingAndCrossAttentions( + last_hidden_state=sequence_output, + pooler_output=pooled_output, + past_key_values=encoder_outputs.past_key_values, + hidden_states=encoder_outputs.hidden_states, + attentions=encoder_outputs.attentions, + cross_attentions=encoder_outputs.cross_attentions, + ) + + +@auto_docstring +class RemBertForMaskedLM(RemBertPreTrainedModel): + def __init__(self, config): + super().__init__(config) + + if config.is_decoder: + logger.warning( + "If you want to use `RemBertForMaskedLM` make sure `config.is_decoder=False` for " + "bi-directional self-attention." + ) + + self.rembert = RemBertModel(config, add_pooling_layer=False) + self.cls = RemBertOnlyMLMHead(config) + + # Initialize weights and apply final processing + self.post_init() + + def get_output_embeddings(self): + return self.cls.predictions.decoder + + def set_output_embeddings(self, new_embeddings): + self.cls.predictions.decoder = new_embeddings + + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.LongTensor | None = None, + token_type_ids: torch.LongTensor | None = None, + position_ids: torch.LongTensor | None = None, + inputs_embeds: torch.FloatTensor | None = None, + encoder_hidden_states: torch.FloatTensor | None = None, + encoder_attention_mask: torch.FloatTensor | None = None, + labels: torch.LongTensor | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + **kwargs, + ) -> tuple | MaskedLMOutput: + r""" + labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Labels for computing the masked language modeling loss. Indices should be in `[-100, 0, ..., + config.vocab_size]` (see `input_ids` docstring) Tokens with indices set to `-100` are ignored (masked), the + loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]`. + """ + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + outputs = self.rembert( + input_ids, + attention_mask=attention_mask, + token_type_ids=token_type_ids, + position_ids=position_ids, + inputs_embeds=inputs_embeds, + encoder_hidden_states=encoder_hidden_states, + encoder_attention_mask=encoder_attention_mask, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + + sequence_output = outputs[0] + prediction_scores = self.cls(sequence_output) + + masked_lm_loss = None + if labels is not None: + loss_fct = CrossEntropyLoss() # -100 index = padding token + masked_lm_loss = loss_fct(prediction_scores.view(-1, self.config.vocab_size), labels.view(-1)) + + if not return_dict: + output = (prediction_scores,) + outputs[2:] + return ((masked_lm_loss,) + output) if masked_lm_loss is not None else output + + return MaskedLMOutput( + loss=masked_lm_loss, + logits=prediction_scores, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + ) + + +@auto_docstring( + custom_intro=""" + RemBERT Model with a `language modeling` head on top for CLM fine-tuning. + """ +) +class RemBertForCausalLM(RemBertPreTrainedModel, GenerationMixin): + def __init__(self, config): + super().__init__(config) + + if not config.is_decoder: + logger.warning("If you want to use `RemBertForCausalLM` as a standalone, add `is_decoder=True.`") + + self.rembert = RemBertModel(config, add_pooling_layer=False) + self.cls = RemBertOnlyMLMHead(config) + + # Initialize weights and apply final processing + self.post_init() + + def get_output_embeddings(self): + return self.cls.predictions.decoder + + def set_output_embeddings(self, new_embeddings): + self.cls.predictions.decoder = new_embeddings + + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.LongTensor | None = None, + token_type_ids: torch.LongTensor | None = None, + position_ids: torch.LongTensor | None = None, + inputs_embeds: torch.FloatTensor | None = None, + encoder_hidden_states: torch.FloatTensor | None = None, + encoder_attention_mask: torch.FloatTensor | None = None, + past_key_values: Cache | None = None, + labels: torch.LongTensor | None = None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + logits_to_keep: int | torch.Tensor = 0, + **kwargs, + ) -> tuple | CausalLMOutputWithCrossAttentions: + r""" + labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Labels for computing the left-to-right language modeling loss (next word prediction). Indices should be in + `[-100, 0, ..., config.vocab_size]` (see `input_ids` docstring) Tokens with indices set to `-100` are + ignored (masked), the loss is only computed for the tokens with labels n `[0, ..., config.vocab_size]`. + + Example: + + ```python + >>> from transformers import AutoTokenizer, RemBertForCausalLM, RemBertConfig + >>> import torch + + >>> tokenizer = AutoTokenizer.from_pretrained("google/rembert") + >>> config = RemBertConfig.from_pretrained("google/rembert") + >>> config.is_decoder = True + >>> model = RemBertForCausalLM.from_pretrained("google/rembert", config=config) + + >>> inputs = tokenizer("Hello, my dog is cute", return_tensors="pt") + >>> outputs = model(**inputs) + + >>> prediction_logits = outputs.logits + ```""" + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + outputs = self.rembert( + input_ids, + attention_mask=attention_mask, + token_type_ids=token_type_ids, + position_ids=position_ids, + inputs_embeds=inputs_embeds, + encoder_hidden_states=encoder_hidden_states, + encoder_attention_mask=encoder_attention_mask, + past_key_values=past_key_values, + use_cache=use_cache, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + + hidden_states = outputs[0] + # Only compute necessary logits, and do not upcast them to float if we are not computing the loss + slice_indices = slice(-logits_to_keep, None) if isinstance(logits_to_keep, int) else logits_to_keep + logits = self.cls(hidden_states[:, slice_indices, :]) + + loss = None + if labels is not None: + loss = self.loss_function(logits=logits, labels=labels, vocab_size=self.config.vocab_size, **kwargs) + + if not return_dict: + output = (logits,) + outputs[2:] + return ((loss,) + output) if loss is not None else output + + return CausalLMOutputWithCrossAttentions( + loss=loss, + logits=logits, + past_key_values=outputs.past_key_values, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + cross_attentions=outputs.cross_attentions, + ) + + +@auto_docstring( + custom_intro=""" + RemBERT Model transformer with a sequence classification/regression head on top (a linear layer on top of the + pooled output) e.g. for GLUE tasks. + """ +) +class RemBertForSequenceClassification(RemBertPreTrainedModel): + def __init__(self, config): + super().__init__(config) + self.num_labels = config.num_labels + self.rembert = RemBertModel(config) + self.dropout = nn.Dropout(config.classifier_dropout_prob) + self.classifier = nn.Linear(config.hidden_size, config.num_labels) + + # Initialize weights and apply final processing + self.post_init() + + @auto_docstring + def forward( + self, + input_ids: torch.FloatTensor | None = None, + attention_mask: torch.FloatTensor | None = None, + token_type_ids: torch.LongTensor | None = None, + position_ids: torch.FloatTensor | None = None, + inputs_embeds: torch.FloatTensor | None = None, + labels: torch.LongTensor | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + **kwargs, + ) -> tuple | SequenceClassifierOutput: + r""" + labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*): + Labels for computing the sequence classification/regression loss. Indices should be in `[0, ..., + config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If + `config.num_labels > 1` a classification loss is computed (Cross-Entropy). + """ + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + outputs = self.rembert( + input_ids, + attention_mask=attention_mask, + token_type_ids=token_type_ids, + position_ids=position_ids, + inputs_embeds=inputs_embeds, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + + pooled_output = outputs[1] + + pooled_output = self.dropout(pooled_output) + logits = self.classifier(pooled_output) + + loss = None + if labels is not None: + if self.config.problem_type is None: + if self.num_labels == 1: + self.config.problem_type = "regression" + elif self.num_labels > 1 and (labels.dtype == torch.long or labels.dtype == torch.int): + self.config.problem_type = "single_label_classification" + else: + self.config.problem_type = "multi_label_classification" + + if self.config.problem_type == "regression": + loss_fct = MSELoss() + if self.num_labels == 1: + loss = loss_fct(logits.squeeze(), labels.squeeze()) + else: + loss = loss_fct(logits, labels) + elif self.config.problem_type == "single_label_classification": + loss_fct = CrossEntropyLoss() + loss = loss_fct(logits.view(-1, self.num_labels), labels.view(-1)) + elif self.config.problem_type == "multi_label_classification": + loss_fct = BCEWithLogitsLoss() + loss = loss_fct(logits, labels) + if not return_dict: + output = (logits,) + outputs[2:] + return ((loss,) + output) if loss is not None else output + + return SequenceClassifierOutput( + loss=loss, + logits=logits, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + ) + + +@auto_docstring +class RemBertForMultipleChoice(RemBertPreTrainedModel): + def __init__(self, config): + super().__init__(config) + + self.rembert = RemBertModel(config) + self.dropout = nn.Dropout(config.classifier_dropout_prob) + self.classifier = nn.Linear(config.hidden_size, 1) + + # Initialize weights and apply final processing + self.post_init() + + @auto_docstring + def forward( + self, + input_ids: torch.FloatTensor | None = None, + attention_mask: torch.FloatTensor | None = None, + token_type_ids: torch.LongTensor | None = None, + position_ids: torch.FloatTensor | None = None, + inputs_embeds: torch.FloatTensor | None = None, + labels: torch.LongTensor | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + **kwargs, + ) -> tuple | MultipleChoiceModelOutput: + r""" + input_ids (`torch.LongTensor` of shape `(batch_size, num_choices, sequence_length)`): + Indices of input sequence tokens in the vocabulary. + + Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and + [`PreTrainedTokenizer.__call__`] for details. + + [What are input IDs?](../glossary#input-ids) + token_type_ids (`torch.LongTensor` of shape `(batch_size, num_choices, sequence_length)`, *optional*): + Segment token indices to indicate first and second portions of the inputs. Indices are selected in `[0, + 1]`: + + - 0 corresponds to a *sentence A* token, + - 1 corresponds to a *sentence B* token. + + [What are token type IDs?](../glossary#token-type-ids) + position_ids (`torch.LongTensor` of shape `(batch_size, num_choices, sequence_length)`, *optional*): + Indices of positions of each input sequence tokens in the position embeddings. Selected in the range `[0, + config.max_position_embeddings - 1]`. + + [What are position IDs?](../glossary#position-ids) + inputs_embeds (`torch.FloatTensor` of shape `(batch_size, num_choices, sequence_length, hidden_size)`, *optional*): + Optionally, instead of passing `input_ids` you can choose to directly pass an embedded representation. This + is useful if you want more control over how to convert *input_ids* indices into associated vectors than the + model's internal embedding lookup matrix. + labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*): + Labels for computing the multiple choice classification loss. Indices should be in `[0, ..., + num_choices-1]` where `num_choices` is the size of the second dimension of the input tensors. (See + `input_ids` above) + """ + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + num_choices = input_ids.shape[1] if input_ids is not None else inputs_embeds.shape[1] + + input_ids = input_ids.view(-1, input_ids.size(-1)) if input_ids is not None else None + attention_mask = attention_mask.view(-1, attention_mask.size(-1)) if attention_mask is not None else None + token_type_ids = token_type_ids.view(-1, token_type_ids.size(-1)) if token_type_ids is not None else None + position_ids = position_ids.view(-1, position_ids.size(-1)) if position_ids is not None else None + inputs_embeds = ( + inputs_embeds.view(-1, inputs_embeds.size(-2), inputs_embeds.size(-1)) + if inputs_embeds is not None + else None + ) + + outputs = self.rembert( + input_ids, + attention_mask=attention_mask, + token_type_ids=token_type_ids, + position_ids=position_ids, + inputs_embeds=inputs_embeds, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + + pooled_output = outputs[1] + + pooled_output = self.dropout(pooled_output) + logits = self.classifier(pooled_output) + reshaped_logits = logits.view(-1, num_choices) + + loss = None + if labels is not None: + loss_fct = CrossEntropyLoss() + loss = loss_fct(reshaped_logits, labels) + + if not return_dict: + output = (reshaped_logits,) + outputs[2:] + return ((loss,) + output) if loss is not None else output + + return MultipleChoiceModelOutput( + loss=loss, + logits=reshaped_logits, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + ) + + +@auto_docstring +class RemBertForTokenClassification(RemBertPreTrainedModel): + def __init__(self, config): + super().__init__(config) + self.num_labels = config.num_labels + + self.rembert = RemBertModel(config, add_pooling_layer=False) + self.dropout = nn.Dropout(config.classifier_dropout_prob) + self.classifier = nn.Linear(config.hidden_size, config.num_labels) + + # Initialize weights and apply final processing + self.post_init() + + @auto_docstring + def forward( + self, + input_ids: torch.FloatTensor | None = None, + attention_mask: torch.FloatTensor | None = None, + token_type_ids: torch.LongTensor | None = None, + position_ids: torch.FloatTensor | None = None, + inputs_embeds: torch.FloatTensor | None = None, + labels: torch.LongTensor | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + **kwargs, + ) -> tuple | TokenClassifierOutput: + r""" + labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Labels for computing the token classification loss. Indices should be in `[0, ..., config.num_labels - 1]`. + """ + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + outputs = self.rembert( + input_ids, + attention_mask=attention_mask, + token_type_ids=token_type_ids, + position_ids=position_ids, + inputs_embeds=inputs_embeds, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + + sequence_output = outputs[0] + + sequence_output = self.dropout(sequence_output) + logits = self.classifier(sequence_output) + + loss = None + if labels is not None: + loss_fct = CrossEntropyLoss() + loss = loss_fct(logits.view(-1, self.num_labels), labels.view(-1)) + + if not return_dict: + output = (logits,) + outputs[2:] + return ((loss,) + output) if loss is not None else output + + return TokenClassifierOutput( + loss=loss, + logits=logits, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + ) + + +@auto_docstring +class RemBertForQuestionAnswering(RemBertPreTrainedModel): + def __init__(self, config): + super().__init__(config) + + self.num_labels = config.num_labels + + self.rembert = RemBertModel(config, add_pooling_layer=False) + self.qa_outputs = nn.Linear(config.hidden_size, config.num_labels) + + # Initialize weights and apply final processing + self.post_init() + + @auto_docstring + def forward( + self, + input_ids: torch.FloatTensor | None = None, + attention_mask: torch.FloatTensor | None = None, + token_type_ids: torch.LongTensor | None = None, + position_ids: torch.FloatTensor | None = None, + inputs_embeds: torch.FloatTensor | None = None, + start_positions: torch.LongTensor | None = None, + end_positions: torch.LongTensor | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + **kwargs, + ) -> tuple | QuestionAnsweringModelOutput: + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + outputs = self.rembert( + input_ids, + attention_mask=attention_mask, + token_type_ids=token_type_ids, + position_ids=position_ids, + inputs_embeds=inputs_embeds, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + + sequence_output = outputs[0] + + logits = self.qa_outputs(sequence_output) + start_logits, end_logits = logits.split(1, dim=-1) + start_logits = start_logits.squeeze(-1) + end_logits = end_logits.squeeze(-1) + + total_loss = None + if start_positions is not None and end_positions is not None: + # If we are on multi-GPU, split add a dimension + if len(start_positions.size()) > 1: + start_positions = start_positions.squeeze(-1) + if len(end_positions.size()) > 1: + end_positions = end_positions.squeeze(-1) + # sometimes the start/end positions are outside our model inputs, we ignore these terms + ignored_index = start_logits.size(1) + start_positions.clamp_(0, ignored_index) + end_positions.clamp_(0, ignored_index) + + loss_fct = CrossEntropyLoss(ignore_index=ignored_index) + start_loss = loss_fct(start_logits, start_positions) + end_loss = loss_fct(end_logits, end_positions) + total_loss = (start_loss + end_loss) / 2 + + if not return_dict: + output = (start_logits, end_logits) + outputs[2:] + return ((total_loss,) + output) if total_loss is not None else output + + return QuestionAnsweringModelOutput( + loss=total_loss, + start_logits=start_logits, + end_logits=end_logits, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + ) + + +__all__ = [ + "RemBertForCausalLM", + "RemBertForMaskedLM", + "RemBertForMultipleChoice", + "RemBertForQuestionAnswering", + "RemBertForSequenceClassification", + "RemBertForTokenClassification", + "RemBertLayer", + "RemBertModel", + "RemBertPreTrainedModel", +] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/rembert/tokenization_rembert.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/rembert/tokenization_rembert.py new file mode 100644 index 0000000000000000000000000000000000000000..d0366018d340cd54b511d14b4e9085ff5f49c3ee --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/rembert/tokenization_rembert.py @@ -0,0 +1,178 @@ +# Copyright 2018 Google AI, Google Brain and the HuggingFace Inc. team. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""Tokenization classes for RemBert model.""" + +from tokenizers import Regex, Tokenizer, decoders, normalizers, pre_tokenizers, processors +from tokenizers.models import Unigram + +from ...tokenization_utils_tokenizers import TokenizersBackend +from ...utils import logging + + +logger = logging.get_logger(__name__) + +VOCAB_FILES_NAMES = {"vocab_file": "sentencepiece.model", "tokenizer_file": "tokenizer.json"} + + +class RemBertTokenizer(TokenizersBackend): + """ + Construct a "fast" RemBert tokenizer (backed by HuggingFace's *tokenizers* library). Based on + [Unigram](https://huggingface.co/docs/tokenizers/python/latest/components.html?highlight=unigram#models). This + tokenizer inherits from [`AlbertTokenizer`] which contains most of the main methods. Users should refer to + this superclass for more information regarding those methods + + Args: + do_lower_case (`bool`, *optional*, defaults to `True`): + Whether or not to lowercase the input when tokenizing. + remove_space (`bool`, *optional*, defaults to `True`): + Whether or not to strip the text when tokenizing (removing excess spaces before and after the string). + keep_accents (`bool`, *optional*, defaults to `False`): + Whether or not to keep accents when tokenizing. + bos_token (`str`, *optional*, defaults to `"[CLS]"`): + The beginning of sequence token that was used during pretraining. Can be used a sequence classifier token. + + + + When building a sequence using special tokens, this is not the token that is used for the beginning of + sequence. The token used is the `cls_token`. + + + + eos_token (`str`, *optional*, defaults to `"[SEP]"`): + The end of sequence token. .. note:: When building a sequence using special tokens, this is not the token + that is used for the end of sequence. The token used is the `sep_token`. + unk_token (`str`, *optional*, defaults to `""`): + The unknown token. A token that is not in the vocabulary cannot be converted to an ID and is set to be this + token instead. + sep_token (`str`, *optional*, defaults to `"[SEP]"`): + The separator token, which is used when building a sequence from multiple sequences, e.g. two sequences for + sequence classification or for a text and a question for question answering. It is also used as the last + token of a sequence built with special tokens. + pad_token (`str`, *optional*, defaults to `""`): + The token used for padding, for example when batching sequences of different lengths. + cls_token (`str`, *optional*, defaults to `"[CLS]"`): + The classifier token which is used when doing sequence classification (classification of the whole sequence + instead of per-token classification). It is the first token of the sequence when built with special tokens. + mask_token (`str`, *optional*, defaults to `"[MASK]"`): + The token used for masking values. This is the token used when training this model with masked language + modeling. This is the token which the model will try to predict. + """ + + vocab_files_names = VOCAB_FILES_NAMES + model_input_names = ["input_ids", "attention_mask"] + model = Unigram + + def __init__( + self, + vocab: str | list[tuple[str, float]] | None = None, + do_lower_case: bool = False, + keep_accents: bool = False, + bos_token: str = "[CLS]", + eos_token: str = "[SEP]", + unk_token: str = "", + sep_token: str = "[SEP]", + pad_token: str = "", + cls_token: str = "[CLS]", + mask_token: str = "[MASK]", + add_prefix_space: bool = True, + remove_space: bool = True, + **kwargs, + ): + self.remove_space = remove_space + self.do_lower_case = do_lower_case + self.keep_accents = keep_accents + + if vocab is not None: + self._vocab_scores = vocab + else: + self._vocab_scores = [ + (str(pad_token), 0.0), + (str(unk_token), 0.0), + (str(cls_token), 0.0), + (str(sep_token), 0.0), + (str(mask_token), 0.0), + ] + + self._tokenizer = Tokenizer( + Unigram( + self._vocab_scores, + unk_id=2, + byte_fallback=False, + ) + ) + + # Build normalizer matching RemBertConverter behavior + # When loading from pretrained, this will be overridden by tokenizer.json config + # When creating from extractor (vocab), this provides equivalent behavior + list_normalizers = [ + normalizers.Replace("``", '"'), + normalizers.Replace("''", '"'), + normalizers.Replace(Regex(" {2,}"), " "), + ] + if not self.keep_accents: + list_normalizers.append(normalizers.NFKD()) + list_normalizers.append(normalizers.StripAccents()) + if self.do_lower_case: + list_normalizers.append(normalizers.Lowercase()) + + # Add Precompiled equivalent (newline conversion + NFKC normalization) + list_normalizers.extend( + [ + normalizers.Replace(Regex(r"[\n\r\t]"), " "), # Precompiled converts newlines/tabs to spaces + normalizers.NFKC(), # Precompiled does NFKC normalization + ] + ) + + self._tokenizer.normalizer = normalizers.Sequence(list_normalizers) + + prepend_scheme = "always" if add_prefix_space else "never" + # Remove WhitespaceSplit - should only have Metaspace (matches SpmConverter) + self._tokenizer.pre_tokenizer = pre_tokenizers.Metaspace(replacement="▁", prepend_scheme=prepend_scheme) + + self._tokenizer.decoder = decoders.Metaspace(replacement="▁", prepend_scheme=prepend_scheme) + super().__init__( + add_prefix_space=add_prefix_space, + do_lower_case=do_lower_case, + keep_accents=keep_accents, + bos_token=bos_token, + eos_token=eos_token, + sep_token=sep_token, + cls_token=cls_token, + unk_token=unk_token, + pad_token=pad_token, + mask_token=mask_token, + remove_space=remove_space, + **kwargs, + ) + + # Set post_processor after super().__init__() so we have token IDs available + # This matches RemBertConverter.post_processor() + cls_token_str = str(cls_token) + sep_token_str = str(sep_token) + cls_token_id = self.convert_tokens_to_ids(cls_token_str) + sep_token_id = self.convert_tokens_to_ids(sep_token_str) + + self._tokenizer.post_processor = processors.TemplateProcessing( + single=f"{cls_token_str}:0 $A:0 {sep_token_str}:0", + pair=f"{cls_token_str}:0 $A:0 {sep_token_str}:0 $B:1 {sep_token_str}:1", + special_tokens=[ + (cls_token_str, cls_token_id), + (sep_token_str, sep_token_id), + ], + ) + + super()._post_init() + + +__all__ = ["RemBertTokenizer"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/resnet/__init__.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/resnet/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..db16908bff31bed48a5627ae7a424d58156f098f --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/resnet/__init__.py @@ -0,0 +1,27 @@ +# Copyright 2024 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from typing import TYPE_CHECKING + +from ...utils import _LazyModule +from ...utils.import_utils import define_import_structure + + +if TYPE_CHECKING: + from .configuration_resnet import * + from .modeling_resnet import * +else: + import sys + + _file = globals()["__file__"] + sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__) diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/resnet/configuration_resnet.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/resnet/configuration_resnet.py new file mode 100644 index 0000000000000000000000000000000000000000..eddd37998e6e7ac3e033d0a12b27c13deb23d776 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/resnet/configuration_resnet.py @@ -0,0 +1,111 @@ +# Copyright 2022 Microsoft Research, Inc. and The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""ResNet model configuration""" + +from ...backbone_utils import BackboneConfigMixin +from ...configuration_utils import PreTrainedConfig +from ...utils import logging + + +logger = logging.get_logger(__name__) + + +class ResNetConfig(BackboneConfigMixin, PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`ResNetModel`]. It is used to instantiate an + ResNet model according to the specified arguments, defining the model architecture. Instantiating a configuration + with the defaults will yield a similar configuration to that of the ResNet + [microsoft/resnet-50](https://huggingface.co/microsoft/resnet-50) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + num_channels (`int`, *optional*, defaults to 3): + The number of input channels. + embedding_size (`int`, *optional*, defaults to 64): + Dimensionality (hidden size) for the embedding layer. + hidden_sizes (`list[int]`, *optional*, defaults to `[256, 512, 1024, 2048]`): + Dimensionality (hidden size) at each stage. + depths (`list[int]`, *optional*, defaults to `[3, 4, 6, 3]`): + Depth (number of layers) for each stage. + layer_type (`str`, *optional*, defaults to `"bottleneck"`): + The layer to use, it can be either `"basic"` (used for smaller models, like resnet-18 or resnet-34) or + `"bottleneck"` (used for larger models like resnet-50 and above). + hidden_act (`str`, *optional*, defaults to `"relu"`): + The non-linear activation function in each block. If string, `"gelu"`, `"relu"`, `"selu"` and `"gelu_new"` + are supported. + downsample_in_first_stage (`bool`, *optional*, defaults to `False`): + If `True`, the first stage will downsample the inputs using a `stride` of 2. + downsample_in_bottleneck (`bool`, *optional*, defaults to `False`): + If `True`, the first conv 1x1 in ResNetBottleNeckLayer will downsample the inputs using a `stride` of 2. + out_features (`list[str]`, *optional*): + If used as backbone, list of features to output. Can be any of `"stem"`, `"stage1"`, `"stage2"`, etc. + (depending on how many stages the model has). If unset and `out_indices` is set, will default to the + corresponding stages. If unset and `out_indices` is unset, will default to the last stage. Must be in the + same order as defined in the `stage_names` attribute. + out_indices (`list[int]`, *optional*): + If used as backbone, list of indices of features to output. Can be any of 0, 1, 2, etc. (depending on how + many stages the model has). If unset and `out_features` is set, will default to the corresponding stages. + If unset and `out_features` is unset, will default to the last stage. Must be in the + same order as defined in the `stage_names` attribute. + + Example: + ```python + >>> from transformers import ResNetConfig, ResNetModel + + >>> # Initializing a ResNet resnet-50 style configuration + >>> configuration = ResNetConfig() + + >>> # Initializing a model (with random weights) from the resnet-50 style configuration + >>> model = ResNetModel(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ``` + """ + + model_type = "resnet" + layer_types = ["basic", "bottleneck"] + + def __init__( + self, + num_channels=3, + embedding_size=64, + hidden_sizes=[256, 512, 1024, 2048], + depths=[3, 4, 6, 3], + layer_type="bottleneck", + hidden_act="relu", + downsample_in_first_stage=False, + downsample_in_bottleneck=False, + out_features=None, + out_indices=None, + **kwargs, + ): + super().__init__(**kwargs) + if layer_type not in self.layer_types: + raise ValueError(f"layer_type={layer_type} is not one of {','.join(self.layer_types)}") + self.num_channels = num_channels + self.embedding_size = embedding_size + self.hidden_sizes = hidden_sizes + self.depths = depths + self.layer_type = layer_type + self.hidden_act = hidden_act + self.downsample_in_first_stage = downsample_in_first_stage + self.downsample_in_bottleneck = downsample_in_bottleneck + self.stage_names = ["stem"] + [f"stage{idx}" for idx in range(1, len(depths) + 1)] + self.set_output_features_output_indices(out_indices=out_indices, out_features=out_features) + + +__all__ = ["ResNetConfig"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/resnet/modeling_resnet.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/resnet/modeling_resnet.py new file mode 100644 index 0000000000000000000000000000000000000000..92a264014c6c5f8f974671b6d03c04a2cb9e3240 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/resnet/modeling_resnet.py @@ -0,0 +1,451 @@ +# Copyright 2022 Microsoft Research, Inc. and The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""PyTorch ResNet model.""" + +import math + +import torch +from torch import Tensor, nn + +from ... import initialization as init +from ...activations import ACT2FN +from ...backbone_utils import BackboneMixin +from ...modeling_outputs import ( + BackboneOutput, + BaseModelOutputWithNoAttention, + BaseModelOutputWithPoolingAndNoAttention, + ImageClassifierOutputWithNoAttention, +) +from ...modeling_utils import PreTrainedModel +from ...utils import auto_docstring, logging +from .configuration_resnet import ResNetConfig + + +logger = logging.get_logger(__name__) + + +class ResNetConvLayer(nn.Module): + def __init__( + self, in_channels: int, out_channels: int, kernel_size: int = 3, stride: int = 1, activation: str = "relu" + ): + super().__init__() + self.convolution = nn.Conv2d( + in_channels, out_channels, kernel_size=kernel_size, stride=stride, padding=kernel_size // 2, bias=False + ) + self.normalization = nn.BatchNorm2d(out_channels) + self.activation = ACT2FN[activation] if activation is not None else nn.Identity() + + def forward(self, input: Tensor) -> Tensor: + hidden_state = self.convolution(input) + hidden_state = self.normalization(hidden_state) + hidden_state = self.activation(hidden_state) + return hidden_state + + +class ResNetEmbeddings(nn.Module): + """ + ResNet Embeddings (stem) composed of a single aggressive convolution. + """ + + def __init__(self, config: ResNetConfig): + super().__init__() + self.embedder = ResNetConvLayer( + config.num_channels, config.embedding_size, kernel_size=7, stride=2, activation=config.hidden_act + ) + self.pooler = nn.MaxPool2d(kernel_size=3, stride=2, padding=1) + self.num_channels = config.num_channels + + def forward(self, pixel_values: Tensor) -> Tensor: + num_channels = pixel_values.shape[1] + if num_channels != self.num_channels: + raise ValueError( + "Make sure that the channel dimension of the pixel values match with the one set in the configuration." + ) + embedding = self.embedder(pixel_values) + embedding = self.pooler(embedding) + return embedding + + +class ResNetShortCut(nn.Module): + """ + ResNet shortcut, used to project the residual features to the correct size. If needed, it is also used to + downsample the input using `stride=2`. + """ + + def __init__(self, in_channels: int, out_channels: int, stride: int = 2): + super().__init__() + self.convolution = nn.Conv2d(in_channels, out_channels, kernel_size=1, stride=stride, bias=False) + self.normalization = nn.BatchNorm2d(out_channels) + + def forward(self, input: Tensor) -> Tensor: + hidden_state = self.convolution(input) + hidden_state = self.normalization(hidden_state) + return hidden_state + + +class ResNetBasicLayer(nn.Module): + """ + A classic ResNet's residual layer composed by two `3x3` convolutions. + """ + + def __init__(self, in_channels: int, out_channels: int, stride: int = 1, activation: str = "relu"): + super().__init__() + should_apply_shortcut = in_channels != out_channels or stride != 1 + self.shortcut = ( + ResNetShortCut(in_channels, out_channels, stride=stride) if should_apply_shortcut else nn.Identity() + ) + self.layer = nn.Sequential( + ResNetConvLayer(in_channels, out_channels, stride=stride), + ResNetConvLayer(out_channels, out_channels, activation=None), + ) + self.activation = ACT2FN[activation] + + def forward(self, hidden_state): + residual = hidden_state + hidden_state = self.layer(hidden_state) + residual = self.shortcut(residual) + hidden_state += residual + hidden_state = self.activation(hidden_state) + return hidden_state + + +class ResNetBottleNeckLayer(nn.Module): + """ + A classic ResNet's bottleneck layer composed by three `3x3` convolutions. + + The first `1x1` convolution reduces the input by a factor of `reduction` in order to make the second `3x3` + convolution faster. The last `1x1` convolution remaps the reduced features to `out_channels`. If + `downsample_in_bottleneck` is true, downsample will be in the first layer instead of the second layer. + """ + + def __init__( + self, + in_channels: int, + out_channels: int, + stride: int = 1, + activation: str = "relu", + reduction: int = 4, + downsample_in_bottleneck: bool = False, + ): + super().__init__() + should_apply_shortcut = in_channels != out_channels or stride != 1 + reduces_channels = out_channels // reduction + self.shortcut = ( + ResNetShortCut(in_channels, out_channels, stride=stride) if should_apply_shortcut else nn.Identity() + ) + self.layer = nn.Sequential( + ResNetConvLayer( + in_channels, reduces_channels, kernel_size=1, stride=stride if downsample_in_bottleneck else 1 + ), + ResNetConvLayer(reduces_channels, reduces_channels, stride=stride if not downsample_in_bottleneck else 1), + ResNetConvLayer(reduces_channels, out_channels, kernel_size=1, activation=None), + ) + self.activation = ACT2FN[activation] + + def forward(self, hidden_state): + residual = hidden_state + hidden_state = self.layer(hidden_state) + residual = self.shortcut(residual) + hidden_state += residual + hidden_state = self.activation(hidden_state) + return hidden_state + + +class ResNetStage(nn.Module): + """ + A ResNet stage composed by stacked layers. + """ + + def __init__( + self, + config: ResNetConfig, + in_channels: int, + out_channels: int, + stride: int = 2, + depth: int = 2, + ): + super().__init__() + + layer = ResNetBottleNeckLayer if config.layer_type == "bottleneck" else ResNetBasicLayer + + if config.layer_type == "bottleneck": + first_layer = layer( + in_channels, + out_channels, + stride=stride, + activation=config.hidden_act, + downsample_in_bottleneck=config.downsample_in_bottleneck, + ) + else: + first_layer = layer(in_channels, out_channels, stride=stride, activation=config.hidden_act) + self.layers = nn.Sequential( + first_layer, *[layer(out_channels, out_channels, activation=config.hidden_act) for _ in range(depth - 1)] + ) + + def forward(self, input: Tensor) -> Tensor: + hidden_state = input + for layer in self.layers: + hidden_state = layer(hidden_state) + return hidden_state + + +class ResNetEncoder(nn.Module): + def __init__(self, config: ResNetConfig): + super().__init__() + self.stages = nn.ModuleList([]) + # based on `downsample_in_first_stage` the first layer of the first stage may or may not downsample the input + self.stages.append( + ResNetStage( + config, + config.embedding_size, + config.hidden_sizes[0], + stride=2 if config.downsample_in_first_stage else 1, + depth=config.depths[0], + ) + ) + in_out_channels = zip(config.hidden_sizes, config.hidden_sizes[1:]) + for (in_channels, out_channels), depth in zip(in_out_channels, config.depths[1:]): + self.stages.append(ResNetStage(config, in_channels, out_channels, depth=depth)) + + def forward( + self, hidden_state: Tensor, output_hidden_states: bool = False, return_dict: bool = True + ) -> BaseModelOutputWithNoAttention: + hidden_states = () if output_hidden_states else None + + for stage_module in self.stages: + if output_hidden_states: + hidden_states = hidden_states + (hidden_state,) + + hidden_state = stage_module(hidden_state) + + if output_hidden_states: + hidden_states = hidden_states + (hidden_state,) + + if not return_dict: + return tuple(v for v in [hidden_state, hidden_states] if v is not None) + + return BaseModelOutputWithNoAttention( + last_hidden_state=hidden_state, + hidden_states=hidden_states, + ) + + +@auto_docstring +class ResNetPreTrainedModel(PreTrainedModel): + config: ResNetConfig + base_model_prefix = "resnet" + main_input_name = "pixel_values" + input_modalities = ("image",) + _no_split_modules = ["ResNetConvLayer", "ResNetShortCut"] + + @torch.no_grad() + def _init_weights(self, module): + if isinstance(module, nn.Conv2d): + init.kaiming_normal_(module.weight, mode="fan_out", nonlinearity="relu") + # copied from the `reset_parameters` method of `class Linear(Module)` in `torch`. + elif isinstance(module, nn.Linear): + init.kaiming_uniform_(module.weight, a=math.sqrt(5)) + if module.bias is not None: + fan_in, _ = torch.nn.init._calculate_fan_in_and_fan_out(module.weight) + bound = 1 / math.sqrt(fan_in) if fan_in > 0 else 0 + init.uniform_(module.bias, -bound, bound) + # We need to check it like that as some Detr models replace the BatchNorm2d by their own + elif "BatchNorm" in module.__class__.__name__: + init.ones_(module.weight) + init.zeros_(module.bias) + init.zeros_(module.running_mean) + init.ones_(module.running_var) + if getattr(module, "num_batches_tracked", None) is not None: + init.zeros_(module.num_batches_tracked) + + +@auto_docstring +class ResNetModel(ResNetPreTrainedModel): + def __init__(self, config): + super().__init__(config) + self.config = config + self.embedder = ResNetEmbeddings(config) + self.encoder = ResNetEncoder(config) + self.pooler = nn.AdaptiveAvgPool2d((1, 1)) + # Initialize weights and apply final processing + self.post_init() + + @auto_docstring + def forward( + self, + pixel_values: Tensor, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + **kwargs, + ) -> BaseModelOutputWithPoolingAndNoAttention: + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + embedding_output = self.embedder(pixel_values) + + encoder_outputs = self.encoder( + embedding_output, output_hidden_states=output_hidden_states, return_dict=return_dict + ) + + last_hidden_state = encoder_outputs[0] + + pooled_output = self.pooler(last_hidden_state) + + if not return_dict: + return (last_hidden_state, pooled_output) + encoder_outputs[1:] + + return BaseModelOutputWithPoolingAndNoAttention( + last_hidden_state=last_hidden_state, + pooler_output=pooled_output, + hidden_states=encoder_outputs.hidden_states, + ) + + +@auto_docstring( + custom_intro=""" + ResNet Model with an image classification head on top (a linear layer on top of the pooled features), e.g. for + ImageNet. + """ +) +class ResNetForImageClassification(ResNetPreTrainedModel): + def __init__(self, config): + super().__init__(config) + self.num_labels = config.num_labels + self.resnet = ResNetModel(config) + # classification head + self.classifier = nn.Sequential( + nn.Flatten(), + nn.Linear(config.hidden_sizes[-1], config.num_labels) if config.num_labels > 0 else nn.Identity(), + ) + # initialize weights and apply final processing + self.post_init() + + @auto_docstring + def forward( + self, + pixel_values: torch.FloatTensor | None = None, + labels: torch.LongTensor | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + **kwargs, + ) -> ImageClassifierOutputWithNoAttention: + r""" + labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*): + Labels for computing the image classification/regression loss. Indices should be in `[0, ..., + config.num_labels - 1]`. If `config.num_labels > 1` a classification loss is computed (Cross-Entropy). + """ + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + outputs = self.resnet(pixel_values, output_hidden_states=output_hidden_states, return_dict=return_dict) + + pooled_output = outputs.pooler_output if return_dict else outputs[1] + + logits = self.classifier(pooled_output) + + loss = None + + if labels is not None: + loss = self.loss_function(labels, logits, self.config) + + if not return_dict: + output = (logits,) + outputs[2:] + return (loss,) + output if loss is not None else output + + return ImageClassifierOutputWithNoAttention(loss=loss, logits=logits, hidden_states=outputs.hidden_states) + + +@auto_docstring( + custom_intro=""" + ResNet backbone, to be used with frameworks like DETR and MaskFormer. + """ +) +class ResNetBackbone(BackboneMixin, ResNetPreTrainedModel): + has_attentions = False + + def __init__(self, config): + super().__init__(config) + + self.num_features = [config.embedding_size] + config.hidden_sizes + self.embedder = ResNetEmbeddings(config) + self.encoder = ResNetEncoder(config) + + # initialize weights and apply final processing + self.post_init() + + @auto_docstring + def forward( + self, + pixel_values: Tensor, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + **kwargs, + ) -> BackboneOutput: + r""" + Examples: + + ```python + >>> from transformers import AutoImageProcessor, AutoBackbone + >>> import torch + >>> from PIL import Image + >>> import httpx + >>> from io import BytesIO + + >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg" + >>> with httpx.stream("GET", url) as response: + ... image = Image.open(BytesIO(response.read())) + + >>> processor = AutoImageProcessor.from_pretrained("microsoft/resnet-50") + >>> model = AutoBackbone.from_pretrained( + ... "microsoft/resnet-50", out_features=["stage1", "stage2", "stage3", "stage4"] + ... ) + + >>> inputs = processor(image, return_tensors="pt") + + >>> outputs = model(**inputs) + >>> feature_maps = outputs.feature_maps + >>> list(feature_maps[-1].shape) + [1, 2048, 7, 7] + ```""" + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + + embedding_output = self.embedder(pixel_values) + + outputs = self.encoder(embedding_output, output_hidden_states=True, return_dict=True) + + hidden_states = outputs.hidden_states + + feature_maps = () + for idx, stage in enumerate(self.stage_names): + if stage in self.out_features: + feature_maps += (hidden_states[idx],) + + if not return_dict: + output = (feature_maps,) + if output_hidden_states: + output += (outputs.hidden_states,) + return output + + return BackboneOutput( + feature_maps=feature_maps, + hidden_states=outputs.hidden_states if output_hidden_states else None, + attentions=None, + ) + + +__all__ = ["ResNetForImageClassification", "ResNetModel", "ResNetPreTrainedModel", "ResNetBackbone"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/roberta/__init__.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/roberta/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..2e8011675176b7e122895b6d6913065f89c2229e --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/roberta/__init__.py @@ -0,0 +1,28 @@ +# Copyright 2024 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from typing import TYPE_CHECKING + +from ...utils import _LazyModule +from ...utils.import_utils import define_import_structure + + +if TYPE_CHECKING: + from .configuration_roberta import * + from .modeling_roberta import * + from .tokenization_roberta import * +else: + import sys + + _file = globals()["__file__"] + sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__) diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/roberta/configuration_roberta.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/roberta/configuration_roberta.py new file mode 100644 index 0000000000000000000000000000000000000000..de7e29a9f103a087eada73a7e4e456a93e1ec865 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/roberta/configuration_roberta.py @@ -0,0 +1,136 @@ +# Copyright 2018 The Google AI Language Team Authors and The HuggingFace Inc. team. +# Copyright (c) 2018, NVIDIA CORPORATION. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""RoBERTa configuration""" + +from ...configuration_utils import PreTrainedConfig +from ...utils import logging + + +logger = logging.get_logger(__name__) + + +class RobertaConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`RobertaModel`]. It is + used to instantiate a RoBERTa model according to the specified arguments, defining the model architecture. + Instantiating a configuration with the defaults will yield a similar configuration to that of the RoBERTa + [FacebookAI/roberta-base](https://huggingface.co/FacebookAI/roberta-base) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + + Args: + vocab_size (`int`, *optional*, defaults to 50265): + Vocabulary size of the RoBERTa model. Defines the number of different tokens that can be represented by the + `inputs_ids` passed when calling [`RobertaModel`]. + hidden_size (`int`, *optional*, defaults to 768): + Dimensionality of the encoder layers and the pooler layer. + num_hidden_layers (`int`, *optional*, defaults to 12): + Number of hidden layers in the Transformer encoder. + num_attention_heads (`int`, *optional*, defaults to 12): + Number of attention heads for each attention layer in the Transformer encoder. + intermediate_size (`int`, *optional*, defaults to 3072): + Dimensionality of the "intermediate" (often named feed-forward) layer in the Transformer encoder. + hidden_act (`str` or `Callable`, *optional*, defaults to `"gelu"`): + The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`, + `"relu"`, `"silu"` and `"gelu_new"` are supported. + hidden_dropout_prob (`float`, *optional*, defaults to 0.1): + The dropout probability for all fully connected layers in the embeddings, encoder, and pooler. + attention_probs_dropout_prob (`float`, *optional*, defaults to 0.1): + The dropout ratio for the attention probabilities. + max_position_embeddings (`int`, *optional*, defaults to 512): + The maximum sequence length that this model might ever be used with. Typically set this to something large + just in case (e.g., 512 or 1024 or 2048). + type_vocab_size (`int`, *optional*, defaults to 2): + The vocabulary size of the `token_type_ids` passed when calling [`RobertaModel`]. + initializer_range (`float`, *optional*, defaults to 0.02): + The standard deviation of the truncated_normal_initializer for initializing all weight matrices. + layer_norm_eps (`float`, *optional*, defaults to 1e-12): + The epsilon used by the layer normalization layers. + is_decoder (`bool`, *optional*, defaults to `False`): + Whether the model is used as a decoder or not. If `False`, the model is used as an encoder. + use_cache (`bool`, *optional*, defaults to `True`): + Whether or not the model should return the last key/values attentions (not used by all models). Only + relevant if `config.is_decoder=True`. + classifier_dropout (`float`, *optional*): + The dropout ratio for the classification head. + + Examples: + + ```python + >>> from transformers import RobertaConfig, RobertaModel + + >>> # Initializing a RoBERTa configuration + >>> configuration = RobertaConfig() + + >>> # Initializing a model (with random weights) from the configuration + >>> model = RobertaModel(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "roberta" + + def __init__( + self, + vocab_size=50265, + hidden_size=768, + num_hidden_layers=12, + num_attention_heads=12, + intermediate_size=3072, + hidden_act="gelu", + hidden_dropout_prob=0.1, + attention_probs_dropout_prob=0.1, + max_position_embeddings=512, + type_vocab_size=2, + initializer_range=0.02, + layer_norm_eps=1e-12, + pad_token_id=1, + bos_token_id=0, + eos_token_id=2, + use_cache=True, + classifier_dropout=None, + is_decoder=False, + add_cross_attention=False, + tie_word_embeddings=True, + **kwargs, + ): + super().__init__(**kwargs) + self.pad_token_id = pad_token_id + self.bos_token_id = bos_token_id + self.eos_token_id = eos_token_id + self.tie_word_embeddings = tie_word_embeddings + + self.is_decoder = is_decoder + self.add_cross_attention = add_cross_attention + self.vocab_size = vocab_size + self.hidden_size = hidden_size + self.num_hidden_layers = num_hidden_layers + self.num_attention_heads = num_attention_heads + self.hidden_act = hidden_act + self.intermediate_size = intermediate_size + self.hidden_dropout_prob = hidden_dropout_prob + self.attention_probs_dropout_prob = attention_probs_dropout_prob + self.max_position_embeddings = max_position_embeddings + self.type_vocab_size = type_vocab_size + self.initializer_range = initializer_range + self.layer_norm_eps = layer_norm_eps + self.use_cache = use_cache + self.classifier_dropout = classifier_dropout + + +__all__ = ["RobertaConfig"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/roberta/modeling_roberta.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/roberta/modeling_roberta.py new file mode 100644 index 0000000000000000000000000000000000000000..f689dd63cc74dfbd4407208fea2e06a444d2c46b --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/roberta/modeling_roberta.py @@ -0,0 +1,1300 @@ +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# This file was automatically generated from src/transformers/models/roberta/modular_roberta.py. +# Do NOT edit this file manually as any edits will be overwritten by the generation of +# the file from the modular. If any change should be done, please apply the change to the +# modular_roberta.py file directly. One of our CI enforces this. +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# Copyright 2018 The Google AI Language Team Authors and The HuggingFace Inc. team. +# Copyright (c) 2018, NVIDIA CORPORATION. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +from collections.abc import Callable + +import torch +import torch.nn as nn +from torch.nn import BCEWithLogitsLoss, CrossEntropyLoss, MSELoss + +from ... import initialization as init +from ...activations import ACT2FN, gelu +from ...cache_utils import Cache, DynamicCache, EncoderDecoderCache +from ...generation import GenerationMixin +from ...masking_utils import create_bidirectional_mask, create_causal_mask +from ...modeling_layers import GradientCheckpointingLayer +from ...modeling_outputs import ( + BaseModelOutputWithPastAndCrossAttentions, + BaseModelOutputWithPoolingAndCrossAttentions, + CausalLMOutputWithCrossAttentions, + MaskedLMOutput, + MultipleChoiceModelOutput, + QuestionAnsweringModelOutput, + SequenceClassifierOutput, + TokenClassifierOutput, +) +from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel +from ...processing_utils import Unpack +from ...pytorch_utils import apply_chunking_to_forward +from ...utils import TransformersKwargs, auto_docstring, logging +from ...utils.generic import can_return_tuple, merge_with_config_defaults +from ...utils.output_capturing import capture_outputs +from .configuration_roberta import RobertaConfig + + +logger = logging.get_logger(__name__) + + +class RobertaEmbeddings(nn.Module): + """Construct the embeddings from word, position and token_type embeddings.""" + + def __init__(self, config): + super().__init__() + self.word_embeddings = nn.Embedding(config.vocab_size, config.hidden_size, padding_idx=config.pad_token_id) + self.token_type_embeddings = nn.Embedding(config.type_vocab_size, config.hidden_size) + + self.LayerNorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps) + self.dropout = nn.Dropout(config.hidden_dropout_prob) + # position_ids (1, len position emb) is contiguous in memory and exported when serialized + self.register_buffer( + "position_ids", torch.arange(config.max_position_embeddings).expand((1, -1)), persistent=False + ) + self.register_buffer( + "token_type_ids", torch.zeros(self.position_ids.size(), dtype=torch.long), persistent=False + ) + + self.padding_idx = config.pad_token_id + self.position_embeddings = nn.Embedding( + config.max_position_embeddings, config.hidden_size, padding_idx=self.padding_idx + ) + + def forward( + self, + input_ids: torch.LongTensor | None = None, + token_type_ids: torch.LongTensor | None = None, + position_ids: torch.LongTensor | None = None, + inputs_embeds: torch.FloatTensor | None = None, + past_key_values_length: int = 0, + ) -> torch.Tensor: + if position_ids is None: + if input_ids is not None: + # Create the position ids from the input token ids. Any padded tokens remain padded. + position_ids = self.create_position_ids_from_input_ids( + input_ids, self.padding_idx, past_key_values_length + ) + else: + position_ids = self.create_position_ids_from_inputs_embeds(inputs_embeds, self.padding_idx) + + if input_ids is not None: + input_shape = input_ids.size() + else: + input_shape = inputs_embeds.size()[:-1] + + batch_size, seq_length = input_shape + + # Setting the token_type_ids to the registered buffer in constructor where it is all zeros, which usually occurs + # when its auto-generated, registered buffer helps users when tracing the model without passing token_type_ids, solves + # issue #5664 + if token_type_ids is None: + if hasattr(self, "token_type_ids"): + # NOTE: We assume either pos ids to have bsz == 1 (broadcastable) or bsz == effective bsz (input_shape[0]) + buffered_token_type_ids = self.token_type_ids.expand(position_ids.shape[0], -1) + buffered_token_type_ids = torch.gather(buffered_token_type_ids, dim=1, index=position_ids) + token_type_ids = buffered_token_type_ids.expand(batch_size, seq_length) + else: + token_type_ids = torch.zeros(input_shape, dtype=torch.long, device=self.position_ids.device) + + if inputs_embeds is None: + inputs_embeds = self.word_embeddings(input_ids) + token_type_embeddings = self.token_type_embeddings(token_type_ids) + embeddings = inputs_embeds + token_type_embeddings + + position_embeddings = self.position_embeddings(position_ids) + embeddings = embeddings + position_embeddings + + embeddings = self.LayerNorm(embeddings) + embeddings = self.dropout(embeddings) + return embeddings + + @staticmethod + def create_position_ids_from_inputs_embeds(inputs_embeds, padding_idx): + """ + We are provided embeddings directly. We cannot infer which are padded so just generate sequential position ids. + + Args: + inputs_embeds: torch.Tensor + + Returns: torch.Tensor + """ + input_shape = inputs_embeds.size()[:-1] + sequence_length = input_shape[1] + + position_ids = torch.arange( + padding_idx + 1, sequence_length + padding_idx + 1, dtype=torch.long, device=inputs_embeds.device + ) + return position_ids.unsqueeze(0).expand(input_shape) + + @staticmethod + def create_position_ids_from_input_ids(input_ids, padding_idx, past_key_values_length=0): + """ + Replace non-padding symbols with their position numbers. Position numbers begin at padding_idx+1. Padding symbols + are ignored. This is modified from fairseq's `utils.make_positions`. + + Args: + x: torch.Tensor x: + + Returns: torch.Tensor + """ + # The series of casts and type-conversions here are carefully balanced to both work with ONNX export and XLA. + mask = input_ids.ne(padding_idx).int() + incremental_indices = (torch.cumsum(mask, dim=1).type_as(mask) + past_key_values_length) * mask + return incremental_indices.long() + padding_idx + + +def eager_attention_forward( + module: nn.Module, + query: torch.Tensor, + key: torch.Tensor, + value: torch.Tensor, + attention_mask: torch.Tensor | None, + scaling: float | None = None, + dropout: float = 0.0, + **kwargs: Unpack[TransformersKwargs], +): + if scaling is None: + scaling = query.size(-1) ** -0.5 + + # Take the dot product between "query" and "key" to get the raw attention scores. + attn_weights = torch.matmul(query, key.transpose(2, 3)) * scaling + + if attention_mask is not None: + attn_weights = attn_weights + attention_mask + + attn_weights = nn.functional.softmax(attn_weights, dim=-1) + attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training) + + attn_output = torch.matmul(attn_weights, value) + attn_output = attn_output.transpose(1, 2).contiguous() + + return attn_output, attn_weights + + +class RobertaSelfAttention(nn.Module): + def __init__(self, config, is_causal=False, layer_idx=None): + super().__init__() + if config.hidden_size % config.num_attention_heads != 0 and not hasattr(config, "embedding_size"): + raise ValueError( + f"The hidden size ({config.hidden_size}) is not a multiple of the number of attention " + f"heads ({config.num_attention_heads})" + ) + self.config = config + + self.num_attention_heads = config.num_attention_heads + self.attention_head_size = int(config.hidden_size / config.num_attention_heads) + self.all_head_size = self.num_attention_heads * self.attention_head_size + self.scaling = self.attention_head_size**-0.5 + + self.query = nn.Linear(config.hidden_size, self.all_head_size) + self.key = nn.Linear(config.hidden_size, self.all_head_size) + self.value = nn.Linear(config.hidden_size, self.all_head_size) + + self.dropout = nn.Dropout(config.attention_probs_dropout_prob) + + self.is_decoder = config.is_decoder + self.is_causal = is_causal + self.layer_idx = layer_idx + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.FloatTensor | None = None, + past_key_values: Cache | None = None, + cache_position: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor]: + input_shape = hidden_states.shape[:-1] + hidden_shape = (*input_shape, -1, self.attention_head_size) + + # get all proj + query_layer = self.query(hidden_states).view(*hidden_shape).transpose(1, 2) + key_layer = self.key(hidden_states).view(*hidden_shape).transpose(1, 2) + value_layer = self.value(hidden_states).view(*hidden_shape).transpose(1, 2) + + if past_key_values is not None: + # decoder-only roberta can have a simple dynamic cache for example + current_past_key_values = past_key_values + if isinstance(past_key_values, EncoderDecoderCache): + current_past_key_values = past_key_values.self_attention_cache + + # save all key/value_layer to cache to be re-used for fast auto-regressive generation + key_layer, value_layer = current_past_key_values.update( + key_layer, + value_layer, + self.layer_idx, + {"cache_position": cache_position}, + ) + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, eager_attention_forward + ) + + attn_output, attn_weights = attention_interface( + self, + query_layer, + key_layer, + value_layer, + attention_mask, + dropout=0.0 if not self.training else self.dropout.p, + scaling=self.scaling, + **kwargs, + ) + attn_output = attn_output.reshape(*input_shape, -1).contiguous() + return attn_output, attn_weights + + +class RobertaCrossAttention(nn.Module): + def __init__(self, config, is_causal=False, layer_idx=None): + super().__init__() + if config.hidden_size % config.num_attention_heads != 0 and not hasattr(config, "embedding_size"): + raise ValueError( + f"The hidden size ({config.hidden_size}) is not a multiple of the number of attention " + f"heads ({config.num_attention_heads})" + ) + self.config = config + + self.num_attention_heads = config.num_attention_heads + self.attention_head_size = int(config.hidden_size / config.num_attention_heads) + self.all_head_size = self.num_attention_heads * self.attention_head_size + self.scaling = self.attention_head_size**-0.5 + + self.query = nn.Linear(config.hidden_size, self.all_head_size) + self.key = nn.Linear(config.hidden_size, self.all_head_size) + self.value = nn.Linear(config.hidden_size, self.all_head_size) + + self.dropout = nn.Dropout(config.attention_probs_dropout_prob) + + self.is_causal = is_causal + self.layer_idx = layer_idx + + def forward( + self, + hidden_states: torch.Tensor, + encoder_hidden_states: torch.FloatTensor | None = None, + attention_mask: torch.FloatTensor | None = None, + past_key_values: EncoderDecoderCache | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor]: + # determine input shapes + bsz, tgt_len = hidden_states.shape[:-1] + src_len = encoder_hidden_states.shape[1] + + q_input_shape = (bsz, tgt_len, -1, self.attention_head_size) + kv_input_shape = (bsz, src_len, -1, self.attention_head_size) + + # get query proj + query_layer = self.query(hidden_states).view(*q_input_shape).transpose(1, 2) + + is_updated = past_key_values.is_updated.get(self.layer_idx) if past_key_values is not None else False + if past_key_values is not None and is_updated: + # reuse k,v, cross_attentions + key_layer = past_key_values.cross_attention_cache.layers[self.layer_idx].keys + value_layer = past_key_values.cross_attention_cache.layers[self.layer_idx].values + else: + key_layer = self.key(encoder_hidden_states).view(*kv_input_shape).transpose(1, 2) + value_layer = self.value(encoder_hidden_states).view(*kv_input_shape).transpose(1, 2) + + if past_key_values is not None: + # save all states to the cache + key_layer, value_layer = past_key_values.cross_attention_cache.update( + key_layer, value_layer, self.layer_idx + ) + # set flag that curr layer for cross-attn is already updated so we can re-use in subsequent calls + past_key_values.is_updated[self.layer_idx] = True + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, eager_attention_forward + ) + + attn_output, attn_weights = attention_interface( + self, + query_layer, + key_layer, + value_layer, + attention_mask, + dropout=0.0 if not self.training else self.dropout.p, + scaling=self.scaling, + **kwargs, + ) + attn_output = attn_output.reshape(bsz, tgt_len, -1).contiguous() + return attn_output, attn_weights + + +class RobertaSelfOutput(nn.Module): + def __init__(self, config): + super().__init__() + self.dense = nn.Linear(config.hidden_size, config.hidden_size) + self.LayerNorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps) + self.dropout = nn.Dropout(config.hidden_dropout_prob) + + def forward(self, hidden_states: torch.Tensor, input_tensor: torch.Tensor) -> torch.Tensor: + hidden_states = self.dense(hidden_states) + hidden_states = self.dropout(hidden_states) + hidden_states = self.LayerNorm(hidden_states + input_tensor) + return hidden_states + + +class RobertaAttention(nn.Module): + def __init__(self, config, is_causal=False, layer_idx=None, is_cross_attention=False): + super().__init__() + self.is_cross_attention = is_cross_attention + attention_class = RobertaCrossAttention if is_cross_attention else RobertaSelfAttention + self.self = attention_class(config, is_causal=is_causal, layer_idx=layer_idx) + self.output = RobertaSelfOutput(config) + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.FloatTensor | None = None, + encoder_hidden_states: torch.FloatTensor | None = None, + encoder_attention_mask: torch.FloatTensor | None = None, + past_key_values: Cache | None = None, + cache_position: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor]: + attention_mask = attention_mask if not self.is_cross_attention else encoder_attention_mask + attention_output, attn_weights = self.self( + hidden_states, + encoder_hidden_states=encoder_hidden_states, + attention_mask=attention_mask, + past_key_values=past_key_values, + cache_position=cache_position, + **kwargs, + ) + attention_output = self.output(attention_output, hidden_states) + return attention_output, attn_weights + + +class RobertaIntermediate(nn.Module): + def __init__(self, config): + super().__init__() + self.dense = nn.Linear(config.hidden_size, config.intermediate_size) + if isinstance(config.hidden_act, str): + self.intermediate_act_fn = ACT2FN[config.hidden_act] + else: + self.intermediate_act_fn = config.hidden_act + + def forward(self, hidden_states: torch.Tensor) -> torch.Tensor: + hidden_states = self.dense(hidden_states) + hidden_states = self.intermediate_act_fn(hidden_states) + return hidden_states + + +class RobertaOutput(nn.Module): + def __init__(self, config): + super().__init__() + self.dense = nn.Linear(config.intermediate_size, config.hidden_size) + self.LayerNorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps) + self.dropout = nn.Dropout(config.hidden_dropout_prob) + + def forward(self, hidden_states: torch.Tensor, input_tensor: torch.Tensor) -> torch.Tensor: + hidden_states = self.dense(hidden_states) + hidden_states = self.dropout(hidden_states) + hidden_states = self.LayerNorm(hidden_states + input_tensor) + return hidden_states + + +class RobertaLayer(GradientCheckpointingLayer): + def __init__(self, config, layer_idx=None): + super().__init__() + self.chunk_size_feed_forward = config.chunk_size_feed_forward + self.seq_len_dim = 1 + self.attention = RobertaAttention(config, is_causal=config.is_decoder, layer_idx=layer_idx) + self.is_decoder = config.is_decoder + self.add_cross_attention = config.add_cross_attention + if self.add_cross_attention: + if not self.is_decoder: + raise ValueError(f"{self} should be used as a decoder model if cross attention is added") + self.crossattention = RobertaAttention( + config, + is_causal=False, + layer_idx=layer_idx, + is_cross_attention=True, + ) + self.intermediate = RobertaIntermediate(config) + self.output = RobertaOutput(config) + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.FloatTensor | None = None, + encoder_hidden_states: torch.FloatTensor | None = None, + encoder_attention_mask: torch.FloatTensor | None = None, + past_key_values: Cache | None = None, + cache_position: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor]: + self_attention_output, _ = self.attention( + hidden_states, + attention_mask, + past_key_values=past_key_values, + cache_position=cache_position, + **kwargs, + ) + attention_output = self_attention_output + + if self.is_decoder and encoder_hidden_states is not None: + if not hasattr(self, "crossattention"): + raise ValueError( + f"If `encoder_hidden_states` are passed, {self} has to be instantiated with cross-attention layers" + " by setting `config.add_cross_attention=True`" + ) + + cross_attention_output, _ = self.crossattention( + self_attention_output, + None, # attention_mask + encoder_hidden_states, + encoder_attention_mask, + past_key_values=past_key_values, + **kwargs, + ) + attention_output = cross_attention_output + + layer_output = apply_chunking_to_forward( + self.feed_forward_chunk, self.chunk_size_feed_forward, self.seq_len_dim, attention_output + ) + return layer_output + + def feed_forward_chunk(self, attention_output): + intermediate_output = self.intermediate(attention_output) + layer_output = self.output(intermediate_output, attention_output) + return layer_output + + +@auto_docstring +class RobertaPreTrainedModel(PreTrainedModel): + config_class = RobertaConfig + base_model_prefix = "roberta" + supports_gradient_checkpointing = True + _supports_flash_attn = True + _supports_sdpa = True + _supports_flex_attn = True + _supports_attention_backend = True + _can_record_outputs = { + "hidden_states": RobertaLayer, + "attentions": RobertaSelfAttention, + "cross_attentions": RobertaCrossAttention, + } + + @torch.no_grad() + def _init_weights(self, module): + """Initialize the weights""" + super()._init_weights(module) + if isinstance(module, RobertaLMHead): + init.zeros_(module.bias) + elif isinstance(module, RobertaEmbeddings): + init.copy_(module.position_ids, torch.arange(module.position_ids.shape[-1]).expand((1, -1))) + init.zeros_(module.token_type_ids) + + +class RobertaEncoder(nn.Module): + def __init__(self, config): + super().__init__() + self.config = config + self.layer = nn.ModuleList([RobertaLayer(config, layer_idx=i) for i in range(config.num_hidden_layers)]) + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.FloatTensor | None = None, + encoder_hidden_states: torch.FloatTensor | None = None, + encoder_attention_mask: torch.FloatTensor | None = None, + past_key_values: Cache | None = None, + use_cache: bool | None = None, + cache_position: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor] | BaseModelOutputWithPastAndCrossAttentions: + for i, layer_module in enumerate(self.layer): + hidden_states = layer_module( + hidden_states, + attention_mask, + encoder_hidden_states, # as a positional argument for gradient checkpointing + encoder_attention_mask=encoder_attention_mask, + past_key_values=past_key_values, + cache_position=cache_position, + **kwargs, + ) + + return BaseModelOutputWithPastAndCrossAttentions( + last_hidden_state=hidden_states, + past_key_values=past_key_values if use_cache else None, + ) + + +class RobertaPooler(nn.Module): + def __init__(self, config): + super().__init__() + self.dense = nn.Linear(config.hidden_size, config.hidden_size) + self.activation = nn.Tanh() + + def forward(self, hidden_states: torch.Tensor) -> torch.Tensor: + # We "pool" the model by simply taking the hidden state corresponding + # to the first token. + first_token_tensor = hidden_states[:, 0] + pooled_output = self.dense(first_token_tensor) + pooled_output = self.activation(pooled_output) + return pooled_output + + +@auto_docstring( + custom_intro=""" + The model can behave as an encoder (with only self-attention) as well as a decoder, in which case a layer of + cross-attention is added between the self-attention layers, following the architecture described in [Attention is + all you need](https://huggingface.co/papers/1706.03762) by Ashish Vaswani, Noam Shazeer, Niki Parmar, Jakob Uszkoreit, + Llion Jones, Aidan N. Gomez, Lukasz Kaiser and Illia Polosukhin. + + To behave as an decoder the model needs to be initialized with the `is_decoder` argument of the configuration set + to `True`. To be used in a Seq2Seq model, the model needs to initialized with both `is_decoder` argument and + `add_cross_attention` set to `True`; an `encoder_hidden_states` is then expected as an input to the forward pass. + """ +) +class RobertaModel(RobertaPreTrainedModel): + _no_split_modules = ["RobertaEmbeddings", "RobertaLayer"] + + def __init__(self, config, add_pooling_layer=True): + r""" + add_pooling_layer (bool, *optional*, defaults to `True`): + Whether to add a pooling layer + """ + super().__init__(config) + self.config = config + self.gradient_checkpointing = False + + self.embeddings = RobertaEmbeddings(config) + self.encoder = RobertaEncoder(config) + + self.pooler = RobertaPooler(config) if add_pooling_layer else None + + # Initialize weights and apply final processing + self.post_init() + + def get_input_embeddings(self): + return self.embeddings.word_embeddings + + def set_input_embeddings(self, value): + self.embeddings.word_embeddings = value + + @merge_with_config_defaults + @capture_outputs + @auto_docstring + def forward( + self, + input_ids: torch.Tensor | None = None, + attention_mask: torch.Tensor | None = None, + token_type_ids: torch.Tensor | None = None, + position_ids: torch.Tensor | None = None, + inputs_embeds: torch.Tensor | None = None, + encoder_hidden_states: torch.Tensor | None = None, + encoder_attention_mask: torch.Tensor | None = None, + past_key_values: Cache | None = None, + use_cache: bool | None = None, + cache_position: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor] | BaseModelOutputWithPoolingAndCrossAttentions: + if self.config.is_decoder: + use_cache = use_cache if use_cache is not None else self.config.use_cache + else: + use_cache = False + + if use_cache and past_key_values is None: + past_key_values = ( + EncoderDecoderCache(DynamicCache(config=self.config), DynamicCache(config=self.config)) + if encoder_hidden_states is not None or self.config.is_encoder_decoder + else DynamicCache(config=self.config) + ) + + if (input_ids is None) ^ (inputs_embeds is not None): + raise ValueError("You must specify exactly one of input_ids or inputs_embeds") + + if input_ids is not None: + device = input_ids.device + seq_length = input_ids.shape[1] + else: + device = inputs_embeds.device + seq_length = inputs_embeds.shape[1] + + past_key_values_length = past_key_values.get_seq_length() if past_key_values is not None else 0 + if cache_position is None: + cache_position = torch.arange(past_key_values_length, past_key_values_length + seq_length, device=device) + + embedding_output = self.embeddings( + input_ids=input_ids, + position_ids=position_ids, + token_type_ids=token_type_ids, + inputs_embeds=inputs_embeds, + past_key_values_length=past_key_values_length, + ) + + attention_mask, encoder_attention_mask = self._create_attention_masks( + attention_mask=attention_mask, + encoder_attention_mask=encoder_attention_mask, + embedding_output=embedding_output, + encoder_hidden_states=encoder_hidden_states, + cache_position=cache_position, + past_key_values=past_key_values, + ) + + encoder_outputs = self.encoder( + embedding_output, + attention_mask=attention_mask, + encoder_hidden_states=encoder_hidden_states, + encoder_attention_mask=encoder_attention_mask, + past_key_values=past_key_values, + use_cache=use_cache, + cache_position=cache_position, + position_ids=position_ids, + **kwargs, + ) + sequence_output = encoder_outputs.last_hidden_state + pooled_output = self.pooler(sequence_output) if self.pooler is not None else None + + return BaseModelOutputWithPoolingAndCrossAttentions( + last_hidden_state=sequence_output, + pooler_output=pooled_output, + past_key_values=encoder_outputs.past_key_values, + ) + + def _create_attention_masks( + self, + attention_mask, + encoder_attention_mask, + embedding_output, + encoder_hidden_states, + cache_position, + past_key_values, + ): + if self.config.is_decoder: + attention_mask = create_causal_mask( + config=self.config, + inputs_embeds=embedding_output, + attention_mask=attention_mask, + cache_position=cache_position, + past_key_values=past_key_values, + ) + else: + attention_mask = create_bidirectional_mask( + config=self.config, + inputs_embeds=embedding_output, + attention_mask=attention_mask, + ) + + if encoder_attention_mask is not None: + encoder_attention_mask = create_bidirectional_mask( + config=self.config, + inputs_embeds=embedding_output, + attention_mask=encoder_attention_mask, + encoder_hidden_states=encoder_hidden_states, + ) + + return attention_mask, encoder_attention_mask + + +@auto_docstring( + custom_intro=""" + RoBERTa Model with a `language modeling` head on top for CLM fine-tuning. + """ +) +class RobertaForCausalLM(RobertaPreTrainedModel, GenerationMixin): + _tied_weights_keys = { + "lm_head.decoder.weight": "roberta.embeddings.word_embeddings.weight", + "lm_head.decoder.bias": "lm_head.bias", + } + + def __init__(self, config): + super().__init__(config) + + if not config.is_decoder: + logger.warning("If you want to use `RobertaLMHeadModel` as a standalone, add `is_decoder=True.`") + + self.roberta = RobertaModel(config, add_pooling_layer=False) + self.lm_head = RobertaLMHead(config) + + # Initialize weights and apply final processing + self.post_init() + + def get_output_embeddings(self): + return self.lm_head.decoder + + def set_output_embeddings(self, new_embeddings): + self.lm_head.decoder = new_embeddings + + @can_return_tuple + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.FloatTensor | None = None, + token_type_ids: torch.LongTensor | None = None, + position_ids: torch.LongTensor | None = None, + inputs_embeds: torch.FloatTensor | None = None, + encoder_hidden_states: torch.FloatTensor | None = None, + encoder_attention_mask: torch.FloatTensor | None = None, + labels: torch.LongTensor | None = None, + past_key_values: tuple[tuple[torch.FloatTensor]] | None = None, + use_cache: bool | None = None, + cache_position: torch.Tensor | None = None, + logits_to_keep: int | torch.Tensor = 0, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor] | CausalLMOutputWithCrossAttentions: + r""" + token_type_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Segment token indices to indicate first and second portions of the inputs. Indices are selected in `[0,1]`: + + - 0 corresponds to a *sentence A* token, + - 1 corresponds to a *sentence B* token. + This parameter can only be used when the model is initialized with `type_vocab_size` parameter with value + >= 2. All the value in this tensor should be always < type_vocab_size. + + [What are token type IDs?](../glossary#token-type-ids) + labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Labels for computing the left-to-right language modeling loss (next word prediction). Indices should be in + `[-100, 0, ..., config.vocab_size]` (see `input_ids` docstring) Tokens with indices set to `-100` are + ignored (masked), the loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]` + + Example: + + ```python + >>> from transformers import AutoTokenizer, RobertaForCausalLM, AutoConfig + >>> import torch + + >>> tokenizer = AutoTokenizer.from_pretrained("FacebookAI/roberta-base") + >>> config = AutoConfig.from_pretrained("FacebookAI/roberta-base") + >>> config.is_decoder = True + >>> model = RobertaForCausalLM.from_pretrained("FacebookAI/roberta-base", config=config) + + >>> inputs = tokenizer("Hello, my dog is cute", return_tensors="pt") + >>> outputs = model(**inputs) + + >>> prediction_logits = outputs.logits + ```""" + if labels is not None: + use_cache = False + + outputs: BaseModelOutputWithPoolingAndCrossAttentions = self.roberta( + input_ids, + attention_mask=attention_mask, + token_type_ids=token_type_ids, + position_ids=position_ids, + inputs_embeds=inputs_embeds, + encoder_hidden_states=encoder_hidden_states, + encoder_attention_mask=encoder_attention_mask, + past_key_values=past_key_values, + use_cache=use_cache, + cache_position=cache_position, + return_dict=True, + **kwargs, + ) + + hidden_states = outputs.last_hidden_state + # Only compute necessary logits, and do not upcast them to float if we are not computing the loss + slice_indices = slice(-logits_to_keep, None) if isinstance(logits_to_keep, int) else logits_to_keep + logits = self.lm_head(hidden_states[:, slice_indices, :]) + + loss = None + if labels is not None: + loss = self.loss_function(logits=logits, labels=labels, vocab_size=self.config.vocab_size, **kwargs) + + return CausalLMOutputWithCrossAttentions( + loss=loss, + logits=logits, + past_key_values=outputs.past_key_values, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + cross_attentions=outputs.cross_attentions, + ) + + +@auto_docstring +class RobertaForMaskedLM(RobertaPreTrainedModel): + _tied_weights_keys = { + "lm_head.decoder.weight": "roberta.embeddings.word_embeddings.weight", + "lm_head.decoder.bias": "lm_head.bias", + } + + def __init__(self, config): + super().__init__(config) + + if config.is_decoder: + logger.warning( + "If you want to use `RobertaForMaskedLM` make sure `config.is_decoder=False` for " + "bi-directional self-attention." + ) + + self.roberta = RobertaModel(config, add_pooling_layer=False) + self.lm_head = RobertaLMHead(config) + + # Initialize weights and apply final processing + self.post_init() + + def get_output_embeddings(self): + return self.lm_head.decoder + + def set_output_embeddings(self, new_embeddings): + self.lm_head.decoder = new_embeddings + + @can_return_tuple + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.FloatTensor | None = None, + token_type_ids: torch.LongTensor | None = None, + position_ids: torch.LongTensor | None = None, + inputs_embeds: torch.FloatTensor | None = None, + encoder_hidden_states: torch.FloatTensor | None = None, + encoder_attention_mask: torch.FloatTensor | None = None, + labels: torch.LongTensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor] | MaskedLMOutput: + r""" + token_type_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Segment token indices to indicate first and second portions of the inputs. Indices are selected in `[0,1]`: + + - 0 corresponds to a *sentence A* token, + - 1 corresponds to a *sentence B* token. + This parameter can only be used when the model is initialized with `type_vocab_size` parameter with value + >= 2. All the value in this tensor should be always < type_vocab_size. + + [What are token type IDs?](../glossary#token-type-ids) + labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Labels for computing the masked language modeling loss. Indices should be in `[-100, 0, ..., + config.vocab_size]` (see `input_ids` docstring) Tokens with indices set to `-100` are ignored (masked), the + loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]` + """ + outputs = self.roberta( + input_ids, + attention_mask=attention_mask, + token_type_ids=token_type_ids, + position_ids=position_ids, + inputs_embeds=inputs_embeds, + encoder_hidden_states=encoder_hidden_states, + encoder_attention_mask=encoder_attention_mask, + return_dict=True, + **kwargs, + ) + sequence_output = outputs[0] + prediction_scores = self.lm_head(sequence_output) + + masked_lm_loss = None + if labels is not None: + # move labels to correct device + labels = labels.to(prediction_scores.device) + loss_fct = CrossEntropyLoss() + masked_lm_loss = loss_fct(prediction_scores.view(-1, self.config.vocab_size), labels.view(-1)) + + return MaskedLMOutput( + loss=masked_lm_loss, + logits=prediction_scores, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + ) + + +class RobertaLMHead(nn.Module): + """Roberta Head for masked language modeling.""" + + def __init__(self, config): + super().__init__() + self.dense = nn.Linear(config.hidden_size, config.hidden_size) + self.layer_norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps) + + self.decoder = nn.Linear(config.hidden_size, config.vocab_size) + self.bias = nn.Parameter(torch.zeros(config.vocab_size)) + + def forward(self, features, **kwargs): + x = self.dense(features) + x = gelu(x) + x = self.layer_norm(x) + + # project back to size of vocabulary with bias + x = self.decoder(x) + + return x + + +@auto_docstring( + custom_intro=""" + RoBERTa Model transformer with a sequence classification/regression head on top (a linear layer on top of the + pooled output) e.g. for GLUE tasks. + """ +) +class RobertaForSequenceClassification(RobertaPreTrainedModel): + def __init__(self, config): + super().__init__(config) + self.num_labels = config.num_labels + self.config = config + + self.roberta = RobertaModel(config, add_pooling_layer=False) + self.classifier = RobertaClassificationHead(config) + + # Initialize weights and apply final processing + self.post_init() + + @can_return_tuple + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.FloatTensor | None = None, + token_type_ids: torch.LongTensor | None = None, + position_ids: torch.LongTensor | None = None, + inputs_embeds: torch.FloatTensor | None = None, + labels: torch.LongTensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor] | SequenceClassifierOutput: + r""" + token_type_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Segment token indices to indicate first and second portions of the inputs. Indices are selected in `[0,1]`: + + - 0 corresponds to a *sentence A* token, + - 1 corresponds to a *sentence B* token. + This parameter can only be used when the model is initialized with `type_vocab_size` parameter with value + >= 2. All the value in this tensor should be always < type_vocab_size. + + [What are token type IDs?](../glossary#token-type-ids) + labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*): + Labels for computing the sequence classification/regression loss. Indices should be in `[0, ..., + config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If + `config.num_labels > 1` a classification loss is computed (Cross-Entropy). + """ + outputs = self.roberta( + input_ids, + attention_mask=attention_mask, + token_type_ids=token_type_ids, + position_ids=position_ids, + inputs_embeds=inputs_embeds, + return_dict=True, + **kwargs, + ) + sequence_output = outputs[0] + logits = self.classifier(sequence_output) + + loss = None + if labels is not None: + # move labels to correct device + labels = labels.to(logits.device) + if self.config.problem_type is None: + if self.num_labels == 1: + self.config.problem_type = "regression" + elif self.num_labels > 1 and (labels.dtype == torch.long or labels.dtype == torch.int): + self.config.problem_type = "single_label_classification" + else: + self.config.problem_type = "multi_label_classification" + + if self.config.problem_type == "regression": + loss_fct = MSELoss() + if self.num_labels == 1: + loss = loss_fct(logits.squeeze(), labels.squeeze()) + else: + loss = loss_fct(logits, labels) + elif self.config.problem_type == "single_label_classification": + loss_fct = CrossEntropyLoss() + loss = loss_fct(logits.view(-1, self.num_labels), labels.view(-1)) + elif self.config.problem_type == "multi_label_classification": + loss_fct = BCEWithLogitsLoss() + loss = loss_fct(logits, labels) + + return SequenceClassifierOutput( + loss=loss, + logits=logits, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + ) + + +@auto_docstring +class RobertaForMultipleChoice(RobertaPreTrainedModel): + def __init__(self, config): + super().__init__(config) + + self.roberta = RobertaModel(config) + self.dropout = nn.Dropout(config.hidden_dropout_prob) + self.classifier = nn.Linear(config.hidden_size, 1) + + # Initialize weights and apply final processing + self.post_init() + + @can_return_tuple + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + token_type_ids: torch.LongTensor | None = None, + attention_mask: torch.FloatTensor | None = None, + labels: torch.LongTensor | None = None, + position_ids: torch.LongTensor | None = None, + inputs_embeds: torch.FloatTensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor] | MultipleChoiceModelOutput: + r""" + input_ids (`torch.LongTensor` of shape `(batch_size, num_choices, sequence_length)`): + Indices of input sequence tokens in the vocabulary. + + Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and + [`PreTrainedTokenizer.__call__`] for details. + + [What are input IDs?](../glossary#input-ids) + token_type_ids (`torch.LongTensor` of shape `(batch_size, num_choices, sequence_length)`, *optional*): + Segment token indices to indicate first and second portions of the inputs. Indices are selected in `[0,1]`: + + - 0 corresponds to a *sentence A* token, + - 1 corresponds to a *sentence B* token. + This parameter can only be used when the model is initialized with `type_vocab_size` parameter with value + >= 2. All the value in this tensor should be always < type_vocab_size. + + [What are token type IDs?](../glossary#token-type-ids) + labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*): + Labels for computing the multiple choice classification loss. Indices should be in `[0, ..., + num_choices-1]` where `num_choices` is the size of the second dimension of the input tensors. (See + `input_ids` above) + position_ids (`torch.LongTensor` of shape `(batch_size, num_choices, sequence_length)`, *optional*): + Indices of positions of each input sequence tokens in the position embeddings. Selected in the range `[0, + config.max_position_embeddings - 1]`. + + [What are position IDs?](../glossary#position-ids) + inputs_embeds (`torch.FloatTensor` of shape `(batch_size, num_choices, sequence_length, hidden_size)`, *optional*): + Optionally, instead of passing `input_ids` you can choose to directly pass an embedded representation. This + is useful if you want more control over how to convert `input_ids` indices into associated vectors than the + model's internal embedding lookup matrix. + """ + num_choices = input_ids.shape[1] if input_ids is not None else inputs_embeds.shape[1] + + flat_input_ids = input_ids.view(-1, input_ids.size(-1)) if input_ids is not None else None + flat_position_ids = position_ids.view(-1, position_ids.size(-1)) if position_ids is not None else None + flat_token_type_ids = token_type_ids.view(-1, token_type_ids.size(-1)) if token_type_ids is not None else None + flat_attention_mask = attention_mask.view(-1, attention_mask.size(-1)) if attention_mask is not None else None + flat_inputs_embeds = ( + inputs_embeds.view(-1, inputs_embeds.size(-2), inputs_embeds.size(-1)) + if inputs_embeds is not None + else None + ) + + outputs = self.roberta( + flat_input_ids, + position_ids=flat_position_ids, + token_type_ids=flat_token_type_ids, + attention_mask=flat_attention_mask, + inputs_embeds=flat_inputs_embeds, + return_dict=True, + **kwargs, + ) + pooled_output = outputs[1] + + pooled_output = self.dropout(pooled_output) + logits = self.classifier(pooled_output) + reshaped_logits = logits.view(-1, num_choices) + + loss = None + if labels is not None: + # move labels to correct device + labels = labels.to(reshaped_logits.device) + loss_fct = CrossEntropyLoss() + loss = loss_fct(reshaped_logits, labels) + + return MultipleChoiceModelOutput( + loss=loss, + logits=reshaped_logits, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + ) + + +@auto_docstring +class RobertaForTokenClassification(RobertaPreTrainedModel): + def __init__(self, config): + super().__init__(config) + self.num_labels = config.num_labels + + self.roberta = RobertaModel(config, add_pooling_layer=False) + classifier_dropout = ( + config.classifier_dropout if config.classifier_dropout is not None else config.hidden_dropout_prob + ) + self.dropout = nn.Dropout(classifier_dropout) + self.classifier = nn.Linear(config.hidden_size, config.num_labels) + + # Initialize weights and apply final processing + self.post_init() + + @can_return_tuple + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.FloatTensor | None = None, + token_type_ids: torch.LongTensor | None = None, + position_ids: torch.LongTensor | None = None, + inputs_embeds: torch.FloatTensor | None = None, + labels: torch.LongTensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor] | TokenClassifierOutput: + r""" + token_type_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Segment token indices to indicate first and second portions of the inputs. Indices are selected in `[0,1]`: + + - 0 corresponds to a *sentence A* token, + - 1 corresponds to a *sentence B* token. + This parameter can only be used when the model is initialized with `type_vocab_size` parameter with value + >= 2. All the value in this tensor should be always < type_vocab_size. + + [What are token type IDs?](../glossary#token-type-ids) + labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Labels for computing the token classification loss. Indices should be in `[0, ..., config.num_labels - 1]`. + """ + outputs = self.roberta( + input_ids, + attention_mask=attention_mask, + token_type_ids=token_type_ids, + position_ids=position_ids, + inputs_embeds=inputs_embeds, + return_dict=True, + **kwargs, + ) + + sequence_output = outputs[0] + + sequence_output = self.dropout(sequence_output) + logits = self.classifier(sequence_output) + + loss = None + if labels is not None: + # move labels to correct device + labels = labels.to(logits.device) + loss_fct = CrossEntropyLoss() + loss = loss_fct(logits.view(-1, self.num_labels), labels.view(-1)) + + return TokenClassifierOutput( + loss=loss, + logits=logits, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + ) + + +class RobertaClassificationHead(nn.Module): + """Head for sentence-level classification tasks.""" + + def __init__(self, config): + super().__init__() + self.dense = nn.Linear(config.hidden_size, config.hidden_size) + classifier_dropout = ( + config.classifier_dropout if config.classifier_dropout is not None else config.hidden_dropout_prob + ) + self.dropout = nn.Dropout(classifier_dropout) + self.out_proj = nn.Linear(config.hidden_size, config.num_labels) + + def forward(self, features, **kwargs): + x = features[:, 0, :] # take token (equiv. to [CLS]) + x = self.dropout(x) + x = self.dense(x) + x = torch.tanh(x) + x = self.dropout(x) + x = self.out_proj(x) + return x + + +@auto_docstring +class RobertaForQuestionAnswering(RobertaPreTrainedModel): + def __init__(self, config): + super().__init__(config) + self.num_labels = config.num_labels + + self.roberta = RobertaModel(config, add_pooling_layer=False) + self.qa_outputs = nn.Linear(config.hidden_size, config.num_labels) + + # Initialize weights and apply final processing + self.post_init() + + @can_return_tuple + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.FloatTensor | None = None, + token_type_ids: torch.LongTensor | None = None, + position_ids: torch.LongTensor | None = None, + inputs_embeds: torch.FloatTensor | None = None, + start_positions: torch.LongTensor | None = None, + end_positions: torch.LongTensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor] | QuestionAnsweringModelOutput: + r""" + token_type_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Segment token indices to indicate first and second portions of the inputs. Indices are selected in `[0,1]`: + + - 0 corresponds to a *sentence A* token, + - 1 corresponds to a *sentence B* token. + This parameter can only be used when the model is initialized with `type_vocab_size` parameter with value + >= 2. All the value in this tensor should be always < type_vocab_size. + + [What are token type IDs?](../glossary#token-type-ids) + """ + outputs = self.roberta( + input_ids, + attention_mask=attention_mask, + token_type_ids=token_type_ids, + position_ids=position_ids, + inputs_embeds=inputs_embeds, + return_dict=True, + **kwargs, + ) + + sequence_output = outputs[0] + + logits = self.qa_outputs(sequence_output) + start_logits, end_logits = logits.split(1, dim=-1) + start_logits = start_logits.squeeze(-1).contiguous() + end_logits = end_logits.squeeze(-1).contiguous() + + total_loss = None + if start_positions is not None and end_positions is not None: + # If we are on multi-GPU, split add a dimension + if len(start_positions.size()) > 1: + start_positions = start_positions.squeeze(-1) + if len(end_positions.size()) > 1: + end_positions = end_positions.squeeze(-1) + # sometimes the start/end positions are outside our model inputs, we ignore these terms + ignored_index = start_logits.size(1) + start_positions = start_positions.clamp(0, ignored_index) + end_positions = end_positions.clamp(0, ignored_index) + + loss_fct = CrossEntropyLoss(ignore_index=ignored_index) + start_loss = loss_fct(start_logits, start_positions) + end_loss = loss_fct(end_logits, end_positions) + total_loss = (start_loss + end_loss) / 2 + + return QuestionAnsweringModelOutput( + loss=total_loss, + start_logits=start_logits, + end_logits=end_logits, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + ) + + +__all__ = [ + "RobertaForCausalLM", + "RobertaForMaskedLM", + "RobertaForMultipleChoice", + "RobertaForQuestionAnswering", + "RobertaForSequenceClassification", + "RobertaForTokenClassification", + "RobertaModel", + "RobertaPreTrainedModel", +] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/roberta/modular_roberta.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/roberta/modular_roberta.py new file mode 100644 index 0000000000000000000000000000000000000000..ef1641fbccd7969c4e3f1982fb6767040efd22cb --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/roberta/modular_roberta.py @@ -0,0 +1,773 @@ +# Copyright 2018 The Google AI Language Team Authors and The HuggingFace Inc. team. +# Copyright (c) 2018, NVIDIA CORPORATION. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""PyTorch RoBERTa model.""" + +import torch +import torch.nn as nn +from torch.nn import BCEWithLogitsLoss, CrossEntropyLoss, MSELoss + +from ... import initialization as init +from ...activations import gelu +from ...generation import GenerationMixin +from ...modeling_outputs import ( + BaseModelOutputWithPoolingAndCrossAttentions, + CausalLMOutputWithCrossAttentions, + MaskedLMOutput, + MultipleChoiceModelOutput, + QuestionAnsweringModelOutput, + SequenceClassifierOutput, + TokenClassifierOutput, +) +from ...modeling_utils import PreTrainedModel +from ...processing_utils import Unpack +from ...utils import TransformersKwargs, auto_docstring, logging +from ...utils.generic import can_return_tuple +from ..bert.modeling_bert import BertCrossAttention, BertEmbeddings, BertLayer, BertModel, BertSelfAttention +from .configuration_roberta import RobertaConfig + + +logger = logging.get_logger(__name__) + + +class RobertaEmbeddings(BertEmbeddings): + def __init__(self, config): + super().__init__(config) + + del self.pad_token_id + del self.position_embeddings + + self.padding_idx = config.pad_token_id + self.position_embeddings = nn.Embedding( + config.max_position_embeddings, config.hidden_size, padding_idx=self.padding_idx + ) + + def forward( + self, + input_ids: torch.LongTensor | None = None, + token_type_ids: torch.LongTensor | None = None, + position_ids: torch.LongTensor | None = None, + inputs_embeds: torch.FloatTensor | None = None, + past_key_values_length: int = 0, + ): + if position_ids is None: + if input_ids is not None: + # Create the position ids from the input token ids. Any padded tokens remain padded. + position_ids = self.create_position_ids_from_input_ids( + input_ids, self.padding_idx, past_key_values_length + ) + else: + position_ids = self.create_position_ids_from_inputs_embeds(inputs_embeds, self.padding_idx) + + if input_ids is not None: + input_shape = input_ids.size() + else: + input_shape = inputs_embeds.size()[:-1] + + batch_size, seq_length = input_shape + + # Setting the token_type_ids to the registered buffer in constructor where it is all zeros, which usually occurs + # when its auto-generated, registered buffer helps users when tracing the model without passing token_type_ids, solves + # issue #5664 + if token_type_ids is None: + if hasattr(self, "token_type_ids"): + # NOTE: We assume either pos ids to have bsz == 1 (broadcastable) or bsz == effective bsz (input_shape[0]) + buffered_token_type_ids = self.token_type_ids.expand(position_ids.shape[0], -1) + buffered_token_type_ids = torch.gather(buffered_token_type_ids, dim=1, index=position_ids) + token_type_ids = buffered_token_type_ids.expand(batch_size, seq_length) + else: + token_type_ids = torch.zeros(input_shape, dtype=torch.long, device=self.position_ids.device) + + if inputs_embeds is None: + inputs_embeds = self.word_embeddings(input_ids) + token_type_embeddings = self.token_type_embeddings(token_type_ids) + embeddings = inputs_embeds + token_type_embeddings + + position_embeddings = self.position_embeddings(position_ids) + embeddings = embeddings + position_embeddings + + embeddings = self.LayerNorm(embeddings) + embeddings = self.dropout(embeddings) + return embeddings + + @staticmethod + def create_position_ids_from_inputs_embeds(inputs_embeds, padding_idx): + """ + We are provided embeddings directly. We cannot infer which are padded so just generate sequential position ids. + + Args: + inputs_embeds: torch.Tensor + + Returns: torch.Tensor + """ + input_shape = inputs_embeds.size()[:-1] + sequence_length = input_shape[1] + + position_ids = torch.arange( + padding_idx + 1, sequence_length + padding_idx + 1, dtype=torch.long, device=inputs_embeds.device + ) + return position_ids.unsqueeze(0).expand(input_shape) + + @staticmethod + def create_position_ids_from_input_ids(input_ids, padding_idx, past_key_values_length=0): + """ + Replace non-padding symbols with their position numbers. Position numbers begin at padding_idx+1. Padding symbols + are ignored. This is modified from fairseq's `utils.make_positions`. + + Args: + x: torch.Tensor x: + + Returns: torch.Tensor + """ + # The series of casts and type-conversions here are carefully balanced to both work with ONNX export and XLA. + mask = input_ids.ne(padding_idx).int() + incremental_indices = (torch.cumsum(mask, dim=1).type_as(mask) + past_key_values_length) * mask + return incremental_indices.long() + padding_idx + + +class RobertaSelfAttention(BertSelfAttention): + pass + + +class RobertaCrossAttention(BertCrossAttention): + pass + + +class RobertaLayer(BertLayer): + pass + + +@auto_docstring +class RobertaPreTrainedModel(PreTrainedModel): + config_class = RobertaConfig + base_model_prefix = "roberta" + supports_gradient_checkpointing = True + _supports_flash_attn = True + _supports_sdpa = True + _supports_flex_attn = True + _supports_attention_backend = True + _can_record_outputs = { + "hidden_states": RobertaLayer, + "attentions": RobertaSelfAttention, + "cross_attentions": RobertaCrossAttention, + } + + @torch.no_grad() + def _init_weights(self, module): + """Initialize the weights""" + super()._init_weights(module) + if isinstance(module, RobertaLMHead): + init.zeros_(module.bias) + elif isinstance(module, RobertaEmbeddings): + init.copy_(module.position_ids, torch.arange(module.position_ids.shape[-1]).expand((1, -1))) + init.zeros_(module.token_type_ids) + + +class RobertaModel(BertModel): + def __init__(self, config, add_pooling_layer=True): + super().__init__(self, config) + + +@auto_docstring( + custom_intro=""" + RoBERTa Model with a `language modeling` head on top for CLM fine-tuning. + """ +) +class RobertaForCausalLM(RobertaPreTrainedModel, GenerationMixin): + _tied_weights_keys = { + "lm_head.decoder.weight": "roberta.embeddings.word_embeddings.weight", + "lm_head.decoder.bias": "lm_head.bias", + } + + def __init__(self, config): + super().__init__(config) + + if not config.is_decoder: + logger.warning("If you want to use `RobertaLMHeadModel` as a standalone, add `is_decoder=True.`") + + self.roberta = RobertaModel(config, add_pooling_layer=False) + self.lm_head = RobertaLMHead(config) + + # Initialize weights and apply final processing + self.post_init() + + def get_output_embeddings(self): + return self.lm_head.decoder + + def set_output_embeddings(self, new_embeddings): + self.lm_head.decoder = new_embeddings + + @can_return_tuple + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.FloatTensor | None = None, + token_type_ids: torch.LongTensor | None = None, + position_ids: torch.LongTensor | None = None, + inputs_embeds: torch.FloatTensor | None = None, + encoder_hidden_states: torch.FloatTensor | None = None, + encoder_attention_mask: torch.FloatTensor | None = None, + labels: torch.LongTensor | None = None, + past_key_values: tuple[tuple[torch.FloatTensor]] | None = None, + use_cache: bool | None = None, + cache_position: torch.Tensor | None = None, + logits_to_keep: int | torch.Tensor = 0, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor] | CausalLMOutputWithCrossAttentions: + r""" + token_type_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Segment token indices to indicate first and second portions of the inputs. Indices are selected in `[0,1]`: + + - 0 corresponds to a *sentence A* token, + - 1 corresponds to a *sentence B* token. + This parameter can only be used when the model is initialized with `type_vocab_size` parameter with value + >= 2. All the value in this tensor should be always < type_vocab_size. + + [What are token type IDs?](../glossary#token-type-ids) + labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Labels for computing the left-to-right language modeling loss (next word prediction). Indices should be in + `[-100, 0, ..., config.vocab_size]` (see `input_ids` docstring) Tokens with indices set to `-100` are + ignored (masked), the loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]` + + Example: + + ```python + >>> from transformers import AutoTokenizer, RobertaForCausalLM, AutoConfig + >>> import torch + + >>> tokenizer = AutoTokenizer.from_pretrained("FacebookAI/roberta-base") + >>> config = AutoConfig.from_pretrained("FacebookAI/roberta-base") + >>> config.is_decoder = True + >>> model = RobertaForCausalLM.from_pretrained("FacebookAI/roberta-base", config=config) + + >>> inputs = tokenizer("Hello, my dog is cute", return_tensors="pt") + >>> outputs = model(**inputs) + + >>> prediction_logits = outputs.logits + ```""" + if labels is not None: + use_cache = False + + outputs: BaseModelOutputWithPoolingAndCrossAttentions = self.roberta( + input_ids, + attention_mask=attention_mask, + token_type_ids=token_type_ids, + position_ids=position_ids, + inputs_embeds=inputs_embeds, + encoder_hidden_states=encoder_hidden_states, + encoder_attention_mask=encoder_attention_mask, + past_key_values=past_key_values, + use_cache=use_cache, + cache_position=cache_position, + return_dict=True, + **kwargs, + ) + + hidden_states = outputs.last_hidden_state + # Only compute necessary logits, and do not upcast them to float if we are not computing the loss + slice_indices = slice(-logits_to_keep, None) if isinstance(logits_to_keep, int) else logits_to_keep + logits = self.lm_head(hidden_states[:, slice_indices, :]) + + loss = None + if labels is not None: + loss = self.loss_function(logits=logits, labels=labels, vocab_size=self.config.vocab_size, **kwargs) + + return CausalLMOutputWithCrossAttentions( + loss=loss, + logits=logits, + past_key_values=outputs.past_key_values, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + cross_attentions=outputs.cross_attentions, + ) + + +@auto_docstring +class RobertaForMaskedLM(RobertaPreTrainedModel): + _tied_weights_keys = { + "lm_head.decoder.weight": "roberta.embeddings.word_embeddings.weight", + "lm_head.decoder.bias": "lm_head.bias", + } + + def __init__(self, config): + super().__init__(config) + + if config.is_decoder: + logger.warning( + "If you want to use `RobertaForMaskedLM` make sure `config.is_decoder=False` for " + "bi-directional self-attention." + ) + + self.roberta = RobertaModel(config, add_pooling_layer=False) + self.lm_head = RobertaLMHead(config) + + # Initialize weights and apply final processing + self.post_init() + + def get_output_embeddings(self): + return self.lm_head.decoder + + def set_output_embeddings(self, new_embeddings): + self.lm_head.decoder = new_embeddings + + @can_return_tuple + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.FloatTensor | None = None, + token_type_ids: torch.LongTensor | None = None, + position_ids: torch.LongTensor | None = None, + inputs_embeds: torch.FloatTensor | None = None, + encoder_hidden_states: torch.FloatTensor | None = None, + encoder_attention_mask: torch.FloatTensor | None = None, + labels: torch.LongTensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor] | MaskedLMOutput: + r""" + token_type_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Segment token indices to indicate first and second portions of the inputs. Indices are selected in `[0,1]`: + + - 0 corresponds to a *sentence A* token, + - 1 corresponds to a *sentence B* token. + This parameter can only be used when the model is initialized with `type_vocab_size` parameter with value + >= 2. All the value in this tensor should be always < type_vocab_size. + + [What are token type IDs?](../glossary#token-type-ids) + labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Labels for computing the masked language modeling loss. Indices should be in `[-100, 0, ..., + config.vocab_size]` (see `input_ids` docstring) Tokens with indices set to `-100` are ignored (masked), the + loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]` + """ + outputs = self.roberta( + input_ids, + attention_mask=attention_mask, + token_type_ids=token_type_ids, + position_ids=position_ids, + inputs_embeds=inputs_embeds, + encoder_hidden_states=encoder_hidden_states, + encoder_attention_mask=encoder_attention_mask, + return_dict=True, + **kwargs, + ) + sequence_output = outputs[0] + prediction_scores = self.lm_head(sequence_output) + + masked_lm_loss = None + if labels is not None: + # move labels to correct device + labels = labels.to(prediction_scores.device) + loss_fct = CrossEntropyLoss() + masked_lm_loss = loss_fct(prediction_scores.view(-1, self.config.vocab_size), labels.view(-1)) + + return MaskedLMOutput( + loss=masked_lm_loss, + logits=prediction_scores, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + ) + + +class RobertaLMHead(nn.Module): + """Roberta Head for masked language modeling.""" + + def __init__(self, config): + super().__init__() + self.dense = nn.Linear(config.hidden_size, config.hidden_size) + self.layer_norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps) + + self.decoder = nn.Linear(config.hidden_size, config.vocab_size) + self.bias = nn.Parameter(torch.zeros(config.vocab_size)) + + def forward(self, features, **kwargs): + x = self.dense(features) + x = gelu(x) + x = self.layer_norm(x) + + # project back to size of vocabulary with bias + x = self.decoder(x) + + return x + + +@auto_docstring( + custom_intro=""" + RoBERTa Model transformer with a sequence classification/regression head on top (a linear layer on top of the + pooled output) e.g. for GLUE tasks. + """ +) +class RobertaForSequenceClassification(RobertaPreTrainedModel): + def __init__(self, config): + super().__init__(config) + self.num_labels = config.num_labels + self.config = config + + self.roberta = RobertaModel(config, add_pooling_layer=False) + self.classifier = RobertaClassificationHead(config) + + # Initialize weights and apply final processing + self.post_init() + + @can_return_tuple + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.FloatTensor | None = None, + token_type_ids: torch.LongTensor | None = None, + position_ids: torch.LongTensor | None = None, + inputs_embeds: torch.FloatTensor | None = None, + labels: torch.LongTensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor] | SequenceClassifierOutput: + r""" + token_type_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Segment token indices to indicate first and second portions of the inputs. Indices are selected in `[0,1]`: + + - 0 corresponds to a *sentence A* token, + - 1 corresponds to a *sentence B* token. + This parameter can only be used when the model is initialized with `type_vocab_size` parameter with value + >= 2. All the value in this tensor should be always < type_vocab_size. + + [What are token type IDs?](../glossary#token-type-ids) + labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*): + Labels for computing the sequence classification/regression loss. Indices should be in `[0, ..., + config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If + `config.num_labels > 1` a classification loss is computed (Cross-Entropy). + """ + outputs = self.roberta( + input_ids, + attention_mask=attention_mask, + token_type_ids=token_type_ids, + position_ids=position_ids, + inputs_embeds=inputs_embeds, + return_dict=True, + **kwargs, + ) + sequence_output = outputs[0] + logits = self.classifier(sequence_output) + + loss = None + if labels is not None: + # move labels to correct device + labels = labels.to(logits.device) + if self.config.problem_type is None: + if self.num_labels == 1: + self.config.problem_type = "regression" + elif self.num_labels > 1 and (labels.dtype == torch.long or labels.dtype == torch.int): + self.config.problem_type = "single_label_classification" + else: + self.config.problem_type = "multi_label_classification" + + if self.config.problem_type == "regression": + loss_fct = MSELoss() + if self.num_labels == 1: + loss = loss_fct(logits.squeeze(), labels.squeeze()) + else: + loss = loss_fct(logits, labels) + elif self.config.problem_type == "single_label_classification": + loss_fct = CrossEntropyLoss() + loss = loss_fct(logits.view(-1, self.num_labels), labels.view(-1)) + elif self.config.problem_type == "multi_label_classification": + loss_fct = BCEWithLogitsLoss() + loss = loss_fct(logits, labels) + + return SequenceClassifierOutput( + loss=loss, + logits=logits, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + ) + + +@auto_docstring +class RobertaForMultipleChoice(RobertaPreTrainedModel): + def __init__(self, config): + super().__init__(config) + + self.roberta = RobertaModel(config) + self.dropout = nn.Dropout(config.hidden_dropout_prob) + self.classifier = nn.Linear(config.hidden_size, 1) + + # Initialize weights and apply final processing + self.post_init() + + @can_return_tuple + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + token_type_ids: torch.LongTensor | None = None, + attention_mask: torch.FloatTensor | None = None, + labels: torch.LongTensor | None = None, + position_ids: torch.LongTensor | None = None, + inputs_embeds: torch.FloatTensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor] | MultipleChoiceModelOutput: + r""" + input_ids (`torch.LongTensor` of shape `(batch_size, num_choices, sequence_length)`): + Indices of input sequence tokens in the vocabulary. + + Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and + [`PreTrainedTokenizer.__call__`] for details. + + [What are input IDs?](../glossary#input-ids) + token_type_ids (`torch.LongTensor` of shape `(batch_size, num_choices, sequence_length)`, *optional*): + Segment token indices to indicate first and second portions of the inputs. Indices are selected in `[0,1]`: + + - 0 corresponds to a *sentence A* token, + - 1 corresponds to a *sentence B* token. + This parameter can only be used when the model is initialized with `type_vocab_size` parameter with value + >= 2. All the value in this tensor should be always < type_vocab_size. + + [What are token type IDs?](../glossary#token-type-ids) + labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*): + Labels for computing the multiple choice classification loss. Indices should be in `[0, ..., + num_choices-1]` where `num_choices` is the size of the second dimension of the input tensors. (See + `input_ids` above) + position_ids (`torch.LongTensor` of shape `(batch_size, num_choices, sequence_length)`, *optional*): + Indices of positions of each input sequence tokens in the position embeddings. Selected in the range `[0, + config.max_position_embeddings - 1]`. + + [What are position IDs?](../glossary#position-ids) + inputs_embeds (`torch.FloatTensor` of shape `(batch_size, num_choices, sequence_length, hidden_size)`, *optional*): + Optionally, instead of passing `input_ids` you can choose to directly pass an embedded representation. This + is useful if you want more control over how to convert `input_ids` indices into associated vectors than the + model's internal embedding lookup matrix. + """ + num_choices = input_ids.shape[1] if input_ids is not None else inputs_embeds.shape[1] + + flat_input_ids = input_ids.view(-1, input_ids.size(-1)) if input_ids is not None else None + flat_position_ids = position_ids.view(-1, position_ids.size(-1)) if position_ids is not None else None + flat_token_type_ids = token_type_ids.view(-1, token_type_ids.size(-1)) if token_type_ids is not None else None + flat_attention_mask = attention_mask.view(-1, attention_mask.size(-1)) if attention_mask is not None else None + flat_inputs_embeds = ( + inputs_embeds.view(-1, inputs_embeds.size(-2), inputs_embeds.size(-1)) + if inputs_embeds is not None + else None + ) + + outputs = self.roberta( + flat_input_ids, + position_ids=flat_position_ids, + token_type_ids=flat_token_type_ids, + attention_mask=flat_attention_mask, + inputs_embeds=flat_inputs_embeds, + return_dict=True, + **kwargs, + ) + pooled_output = outputs[1] + + pooled_output = self.dropout(pooled_output) + logits = self.classifier(pooled_output) + reshaped_logits = logits.view(-1, num_choices) + + loss = None + if labels is not None: + # move labels to correct device + labels = labels.to(reshaped_logits.device) + loss_fct = CrossEntropyLoss() + loss = loss_fct(reshaped_logits, labels) + + return MultipleChoiceModelOutput( + loss=loss, + logits=reshaped_logits, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + ) + + +@auto_docstring +class RobertaForTokenClassification(RobertaPreTrainedModel): + def __init__(self, config): + super().__init__(config) + self.num_labels = config.num_labels + + self.roberta = RobertaModel(config, add_pooling_layer=False) + classifier_dropout = ( + config.classifier_dropout if config.classifier_dropout is not None else config.hidden_dropout_prob + ) + self.dropout = nn.Dropout(classifier_dropout) + self.classifier = nn.Linear(config.hidden_size, config.num_labels) + + # Initialize weights and apply final processing + self.post_init() + + @can_return_tuple + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.FloatTensor | None = None, + token_type_ids: torch.LongTensor | None = None, + position_ids: torch.LongTensor | None = None, + inputs_embeds: torch.FloatTensor | None = None, + labels: torch.LongTensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor] | TokenClassifierOutput: + r""" + token_type_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Segment token indices to indicate first and second portions of the inputs. Indices are selected in `[0,1]`: + + - 0 corresponds to a *sentence A* token, + - 1 corresponds to a *sentence B* token. + This parameter can only be used when the model is initialized with `type_vocab_size` parameter with value + >= 2. All the value in this tensor should be always < type_vocab_size. + + [What are token type IDs?](../glossary#token-type-ids) + labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Labels for computing the token classification loss. Indices should be in `[0, ..., config.num_labels - 1]`. + """ + outputs = self.roberta( + input_ids, + attention_mask=attention_mask, + token_type_ids=token_type_ids, + position_ids=position_ids, + inputs_embeds=inputs_embeds, + return_dict=True, + **kwargs, + ) + + sequence_output = outputs[0] + + sequence_output = self.dropout(sequence_output) + logits = self.classifier(sequence_output) + + loss = None + if labels is not None: + # move labels to correct device + labels = labels.to(logits.device) + loss_fct = CrossEntropyLoss() + loss = loss_fct(logits.view(-1, self.num_labels), labels.view(-1)) + + return TokenClassifierOutput( + loss=loss, + logits=logits, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + ) + + +class RobertaClassificationHead(nn.Module): + """Head for sentence-level classification tasks.""" + + def __init__(self, config): + super().__init__() + self.dense = nn.Linear(config.hidden_size, config.hidden_size) + classifier_dropout = ( + config.classifier_dropout if config.classifier_dropout is not None else config.hidden_dropout_prob + ) + self.dropout = nn.Dropout(classifier_dropout) + self.out_proj = nn.Linear(config.hidden_size, config.num_labels) + + def forward(self, features, **kwargs): + x = features[:, 0, :] # take token (equiv. to [CLS]) + x = self.dropout(x) + x = self.dense(x) + x = torch.tanh(x) + x = self.dropout(x) + x = self.out_proj(x) + return x + + +@auto_docstring +class RobertaForQuestionAnswering(RobertaPreTrainedModel): + def __init__(self, config): + super().__init__(config) + self.num_labels = config.num_labels + + self.roberta = RobertaModel(config, add_pooling_layer=False) + self.qa_outputs = nn.Linear(config.hidden_size, config.num_labels) + + # Initialize weights and apply final processing + self.post_init() + + @can_return_tuple + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.FloatTensor | None = None, + token_type_ids: torch.LongTensor | None = None, + position_ids: torch.LongTensor | None = None, + inputs_embeds: torch.FloatTensor | None = None, + start_positions: torch.LongTensor | None = None, + end_positions: torch.LongTensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor] | QuestionAnsweringModelOutput: + r""" + token_type_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Segment token indices to indicate first and second portions of the inputs. Indices are selected in `[0,1]`: + + - 0 corresponds to a *sentence A* token, + - 1 corresponds to a *sentence B* token. + This parameter can only be used when the model is initialized with `type_vocab_size` parameter with value + >= 2. All the value in this tensor should be always < type_vocab_size. + + [What are token type IDs?](../glossary#token-type-ids) + """ + outputs = self.roberta( + input_ids, + attention_mask=attention_mask, + token_type_ids=token_type_ids, + position_ids=position_ids, + inputs_embeds=inputs_embeds, + return_dict=True, + **kwargs, + ) + + sequence_output = outputs[0] + + logits = self.qa_outputs(sequence_output) + start_logits, end_logits = logits.split(1, dim=-1) + start_logits = start_logits.squeeze(-1).contiguous() + end_logits = end_logits.squeeze(-1).contiguous() + + total_loss = None + if start_positions is not None and end_positions is not None: + # If we are on multi-GPU, split add a dimension + if len(start_positions.size()) > 1: + start_positions = start_positions.squeeze(-1) + if len(end_positions.size()) > 1: + end_positions = end_positions.squeeze(-1) + # sometimes the start/end positions are outside our model inputs, we ignore these terms + ignored_index = start_logits.size(1) + start_positions = start_positions.clamp(0, ignored_index) + end_positions = end_positions.clamp(0, ignored_index) + + loss_fct = CrossEntropyLoss(ignore_index=ignored_index) + start_loss = loss_fct(start_logits, start_positions) + end_loss = loss_fct(end_logits, end_positions) + total_loss = (start_loss + end_loss) / 2 + + return QuestionAnsweringModelOutput( + loss=total_loss, + start_logits=start_logits, + end_logits=end_logits, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + ) + + +__all__ = [ + "RobertaForCausalLM", + "RobertaForMaskedLM", + "RobertaForMultipleChoice", + "RobertaForQuestionAnswering", + "RobertaForSequenceClassification", + "RobertaForTokenClassification", + "RobertaModel", + "RobertaPreTrainedModel", +] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/roberta/tokenization_roberta.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/roberta/tokenization_roberta.py new file mode 100644 index 0000000000000000000000000000000000000000..40b4e78426f6152b9ac8eb2d43b48e757b508f67 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/roberta/tokenization_roberta.py @@ -0,0 +1,178 @@ +# Copyright 2018 The Open AI Team Authors and The HuggingFace Inc. team. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""Tokenization classes for RoBERTa.""" + +from tokenizers import Tokenizer, decoders, pre_tokenizers, processors +from tokenizers.models import BPE + +from ...tokenization_utils_tokenizers import TokenizersBackend +from ...utils import logging + + +logger = logging.get_logger(__name__) + +VOCAB_FILES_NAMES = {"vocab_file": "vocab.json", "merges_file": "merges.txt", "tokenizer_file": "tokenizer.json"} + + +class RobertaTokenizer(TokenizersBackend): + r""" + Construct a RoBERTa tokenizer (backed by HuggingFace's tokenizers library). Based on Byte-Pair-Encoding. + + This tokenizer has been trained to treat spaces like parts of the tokens (a bit like sentencepiece) so a word will + be encoded differently whether it is at the beginning of the sentence (without space) or not: + + ```python + >>> from transformers import RobertaTokenizer + + >>> tokenizer = RobertaTokenizer.from_pretrained("FacebookAI/roberta-base") + >>> tokenizer("Hello world")["input_ids"] + [0, 31414, 232, 2] + + >>> tokenizer(" Hello world")["input_ids"] + [0, 20920, 232, 2] + ``` + + You can get around that behavior by passing `add_prefix_space=True` when instantiating this tokenizer or when you + call it on some text, but since the model was not pretrained this way, it might yield a decrease in performance. + + + + When used with `is_split_into_words=True`, this tokenizer needs to be instantiated with `add_prefix_space=True`. + + + + This tokenizer inherits from [`TokenizersBackend`] which contains most of the main methods. Users should refer to + this superclass for more information regarding those methods. + + Args: + vocab (`str`, `dict` or `list`, *optional*): + Custom vocabulary dictionary. If not provided, vocabulary is loaded from vocab_file. + merges (`str` or `list`, *optional*): + Custom merges list. If not provided, merges are loaded from merges_file. + errors (`str`, *optional*, defaults to `"replace"`): + Paradigm to follow when decoding bytes to UTF-8. See + [bytes.decode](https://docs.python.org/3/library/stdtypes.html#bytes.decode) for more information. + bos_token (`str`, *optional*, defaults to `""`): + The beginning of sequence token that was used during pretraining. Can be used a sequence classifier token. + + + + When building a sequence using special tokens, this is not the token that is used for the beginning of + sequence. The token used is the `cls_token`. + + + + eos_token (`str`, *optional*, defaults to `""`): + The end of sequence token. + + + + When building a sequence using special tokens, this is not the token that is used for the end of sequence. + The token used is the `sep_token`. + + + + sep_token (`str`, *optional*, defaults to `""`): + The separator token, which is used when building a sequence from multiple sequences, e.g. two sequences for + sequence classification or for a text and a question for question answering. It is also used as the last + token of a sequence built with special tokens. + cls_token (`str`, *optional*, defaults to `""`): + The classifier token which is used when doing sequence classification (classification of the whole sequence + instead of per-token classification). It is the first token of the sequence when built with special tokens. + unk_token (`str`, *optional*, defaults to `""`): + The unknown token. A token that is not in the vocabulary cannot be converted to an ID and is set to be this + token instead. + pad_token (`str`, *optional*, defaults to `""`): + The token used for padding, for example when batching sequences of different lengths. + mask_token (`str`, *optional*, defaults to `""`): + The token used for masking values. This is the token used when training this model with masked language + modeling. This is the token which the model will try to predict. + add_prefix_space (`bool`, *optional*, defaults to `False`): + Whether or not to add an initial space to the input. This allows to treat the leading word just as any + other word. (RoBERTa tokenizer detect beginning of words by the preceding space). + trim_offsets (`bool`, *optional*, defaults to `True`): + Whether the post processing step should trim offsets to avoid including whitespaces. + """ + + vocab_files_names = VOCAB_FILES_NAMES + model_input_names = ["input_ids", "attention_mask"] + model = BPE + + def __init__( + self, + vocab: str | dict[str, int] | None = None, + merges: str | list[str] | None = None, + errors: str = "replace", + bos_token: str = "", + eos_token: str = "", + sep_token: str = "", + cls_token: str = "", + unk_token: str = "", + pad_token: str = "", + mask_token: str = "", + add_prefix_space: bool = False, + trim_offsets: bool = True, + **kwargs, + ): + self.add_prefix_space = add_prefix_space + self.trim_offsets = trim_offsets + + if vocab is None: + vocab = { + str(pad_token): 0, + str(unk_token): 1, + str(cls_token): 2, + str(sep_token): 3, + str(mask_token): 4, + } + self._vocab = vocab + + self._merges = merges or [] + + self._tokenizer = Tokenizer( + BPE( + vocab=self._vocab, + merges=self._merges, + dropout=None, + continuing_subword_prefix="", + end_of_word_suffix="", + fuse_unk=False, + ) + ) + + self._tokenizer.pre_tokenizer = pre_tokenizers.ByteLevel(add_prefix_space=add_prefix_space) + self._tokenizer.decoder = decoders.ByteLevel() + + super().__init__( + errors=errors, + bos_token=bos_token, + eos_token=eos_token, + sep_token=sep_token, + cls_token=cls_token, + unk_token=unk_token, + pad_token=pad_token, + mask_token=mask_token, + add_prefix_space=add_prefix_space, + trim_offsets=trim_offsets, + **kwargs, + ) + self._tokenizer.post_processor = processors.RobertaProcessing( + sep=(str(sep_token), self.sep_token_id), + cls=(str(cls_token), self.cls_token_id), + add_prefix_space=add_prefix_space, + trim_offsets=trim_offsets, + ) + + +__all__ = ["RobertaTokenizer"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/roberta/tokenization_roberta_old.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/roberta/tokenization_roberta_old.py new file mode 100644 index 0000000000000000000000000000000000000000..3dceda4c310fe3b53b97048f91ed024bc6503c1f --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/roberta/tokenization_roberta_old.py @@ -0,0 +1,262 @@ +# Copyright 2018 The Open AI Team Authors and The HuggingFace Inc. team. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""Fast Tokenization classes for RoBERTa.""" + +import json + +from tokenizers import processors + +from ...tokenization_utils_base import AddedToken, BatchEncoding +from ...tokenization_utils_tokenizers import PreTrainedTokenizerFast +from ...utils import logging +from .tokenization_roberta import RobertaTokenizer + + +logger = logging.get_logger(__name__) + +VOCAB_FILES_NAMES = {"vocab_file": "vocab.json", "merges_file": "merges.txt", "tokenizer_file": "tokenizer.json"} + + +class RobertaTokenizerFast(PreTrainedTokenizerFast): + """ + Construct a "fast" RoBERTa tokenizer (backed by HuggingFace's *tokenizers* library), derived from the GPT-2 + tokenizer, using byte-level Byte-Pair-Encoding. + + This tokenizer has been trained to treat spaces like parts of the tokens (a bit like sentencepiece) so a word will + be encoded differently whether it is at the beginning of the sentence (without space) or not: + + ```python + >>> from transformers import RobertaTokenizerFast + + >>> tokenizer = RobertaTokenizerFast.from_pretrained("FacebookAI/roberta-base") + >>> tokenizer("Hello world")["input_ids"] + [0, 31414, 232, 2] + + >>> tokenizer(" Hello world")["input_ids"] + [0, 20920, 232, 2] + ``` + + You can get around that behavior by passing `add_prefix_space=True` when instantiating this tokenizer or when you + call it on some text, but since the model was not pretrained this way, it might yield a decrease in performance. + + + + When used with `is_split_into_words=True`, this tokenizer needs to be instantiated with `add_prefix_space=True`. + + + + This tokenizer inherits from [`PreTrainedTokenizerFast`] which contains most of the main methods. Users should + refer to this superclass for more information regarding those methods. + + Args: + vocab_file (`str`): + Path to the vocabulary file. + merges_file (`str`): + Path to the merges file. + errors (`str`, *optional*, defaults to `"replace"`): + Paradigm to follow when decoding bytes to UTF-8. See + [bytes.decode](https://docs.python.org/3/library/stdtypes.html#bytes.decode) for more information. + bos_token (`str`, *optional*, defaults to `""`): + The beginning of sequence token that was used during pretraining. Can be used a sequence classifier token. + + + + When building a sequence using special tokens, this is not the token that is used for the beginning of + sequence. The token used is the `cls_token`. + + + + eos_token (`str`, *optional*, defaults to `""`): + The end of sequence token. + + + + When building a sequence using special tokens, this is not the token that is used for the end of sequence. + The token used is the `sep_token`. + + + + sep_token (`str`, *optional*, defaults to `""`): + The separator token, which is used when building a sequence from multiple sequences, e.g. two sequences for + sequence classification or for a text and a question for question answering. It is also used as the last + token of a sequence built with special tokens. + cls_token (`str`, *optional*, defaults to `""`): + The classifier token which is used when doing sequence classification (classification of the whole sequence + instead of per-token classification). It is the first token of the sequence when built with special tokens. + unk_token (`str`, *optional*, defaults to `""`): + The unknown token. A token that is not in the vocabulary cannot be converted to an ID and is set to be this + token instead. + pad_token (`str`, *optional*, defaults to `""`): + The token used for padding, for example when batching sequences of different lengths. + mask_token (`str`, *optional*, defaults to `""`): + The token used for masking values. This is the token used when training this model with masked language + modeling. This is the token which the model will try to predict. + add_prefix_space (`bool`, *optional*, defaults to `False`): + Whether or not to add an initial space to the input. This allows to treat the leading word just as any + other word. (RoBERTa tokenizer detect beginning of words by the preceding space). + trim_offsets (`bool`, *optional*, defaults to `True`): + Whether the post processing step should trim offsets to avoid including whitespaces. + """ + + vocab_files_names = VOCAB_FILES_NAMES + model_input_names = ["input_ids", "attention_mask"] + slow_tokenizer_class = RobertaTokenizer + + def __init__( + self, + vocab_file=None, + merges_file=None, + tokenizer_file=None, + errors="replace", + bos_token="", + eos_token="", + sep_token="", + cls_token="", + unk_token="", + pad_token="", + mask_token="", + add_prefix_space=False, + trim_offsets=True, + **kwargs, + ): + mask_token = ( + AddedToken(mask_token, lstrip=True, rstrip=False, normalized=False) + if isinstance(mask_token, str) + else mask_token + ) + super().__init__( + vocab_file, + merges_file, + tokenizer_file=tokenizer_file, + errors=errors, + bos_token=bos_token, + eos_token=eos_token, + sep_token=sep_token, + cls_token=cls_token, + unk_token=unk_token, + pad_token=pad_token, + mask_token=mask_token, + add_prefix_space=add_prefix_space, + trim_offsets=trim_offsets, + **kwargs, + ) + + tokenizer_component = "post_processor" + tokenizer_component_instance = getattr(self.backend_tokenizer, tokenizer_component, None) + if tokenizer_component_instance: + state = json.loads(tokenizer_component_instance.__getstate__()) + + # The lists 'sep' and 'cls' must be cased in tuples for the object `post_processor_class` + if "sep" in state: + state["sep"] = tuple(state["sep"]) + if "cls" in state: + state["cls"] = tuple(state["cls"]) + + changes_to_apply = False + + if state.get("add_prefix_space", add_prefix_space) != add_prefix_space: + state["add_prefix_space"] = add_prefix_space + changes_to_apply = True + + if state.get("trim_offsets", trim_offsets) != trim_offsets: + state["trim_offsets"] = trim_offsets + changes_to_apply = True + + if changes_to_apply: + component_class = getattr(processors, state.pop("type")) + new_value = component_class(**state) + setattr(self.backend_tokenizer, tokenizer_component, new_value) + + @property + def mask_token(self) -> str: + """ + `str`: Mask token, to use when training a model with masked-language modeling. Log an error if used while not + having been set. + + Roberta tokenizer has a special mask token to be usable in the fill-mask pipeline. The mask token will greedily + comprise the space before the **. + """ + if self._mask_token is None: + if self.verbose: + logger.error("Using mask_token, but it is not set yet.") + return None + return str(self._mask_token) + + @mask_token.setter + def mask_token(self, value): + """ + Overriding the default behavior of the mask token to have it eat the space before it. + + This is needed to preserve backward compatibility with all the previously used models based on Roberta. + """ + # Mask token behave like a normal word, i.e. include the space before it + # So we set lstrip to True + value = AddedToken(value, lstrip=True, rstrip=False) if isinstance(value, str) else value + self._mask_token = value + + def _batch_encode_plus(self, *args, **kwargs) -> BatchEncoding: + is_split_into_words = kwargs.get("is_split_into_words", False) + assert self.add_prefix_space or not is_split_into_words, ( + f"You need to instantiate {self.__class__.__name__} with add_prefix_space=True " + "to use it with pretokenized inputs." + ) + + return super()._batch_encode_plus(*args, **kwargs) + + def _encode_plus(self, *args, **kwargs) -> BatchEncoding: + is_split_into_words = kwargs.get("is_split_into_words", False) + + assert self.add_prefix_space or not is_split_into_words, ( + f"You need to instantiate {self.__class__.__name__} with add_prefix_space=True " + "to use it with pretokenized inputs." + ) + + return super()._encode_plus(*args, **kwargs) + + def save_vocabulary(self, save_directory: str, filename_prefix: str | None = None) -> tuple[str]: + files = self._tokenizer.model.save(save_directory, name=filename_prefix) + return tuple(files) + + def build_inputs_with_special_tokens(self, token_ids_0, token_ids_1=None): + output = [self.bos_token_id] + token_ids_0 + [self.eos_token_id] + if token_ids_1 is None: + return output + + return output + [self.eos_token_id] + token_ids_1 + [self.eos_token_id] + + def create_token_type_ids_from_sequences( + self, token_ids_0: list[int], token_ids_1: list[int] | None = None + ) -> list[int]: + """ + Create a mask from the two sequences passed to be used in a sequence-pair classification task. RoBERTa does not + make use of token type ids, therefore a list of zeros is returned. + + Args: + token_ids_0 (`list[int]`): + List of IDs. + token_ids_1 (`list[int]`, *optional*): + Optional second list of IDs for sequence pairs. + + Returns: + `list[int]`: List of zeros. + """ + sep = [self.sep_token_id] + cls = [self.cls_token_id] + + if token_ids_1 is None: + return len(cls + token_ids_0 + sep) * [0] + return len(cls + token_ids_0 + sep + sep + token_ids_1 + sep) * [0] + + +__all__ = ["RobertaTokenizerFast"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/roberta_prelayernorm/__init__.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/roberta_prelayernorm/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..369698d84ba093652e98f7c23dacbce2663f2269 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/roberta_prelayernorm/__init__.py @@ -0,0 +1,27 @@ +# Copyright 2024 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from typing import TYPE_CHECKING + +from ...utils import _LazyModule +from ...utils.import_utils import define_import_structure + + +if TYPE_CHECKING: + from .configuration_roberta_prelayernorm import * + from .modeling_roberta_prelayernorm import * +else: + import sys + + _file = globals()["__file__"] + sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__) diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/roberta_prelayernorm/configuration_roberta_prelayernorm.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/roberta_prelayernorm/configuration_roberta_prelayernorm.py new file mode 100644 index 0000000000000000000000000000000000000000..ca136258a9f488d033c93d50c46396e3d99b4dc1 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/roberta_prelayernorm/configuration_roberta_prelayernorm.py @@ -0,0 +1,137 @@ +# Copyright 2022 The Google AI Language Team Authors and The HuggingFace Inc. team. +# All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""RoBERTa-PreLayerNorm configuration""" + +from ...configuration_utils import PreTrainedConfig +from ...utils import logging + + +logger = logging.get_logger(__name__) + + +# Copied from transformers.models.roberta.configuration_roberta.RobertaConfig with FacebookAI/roberta-base->andreasmadsen/efficient_mlm_m0.40,RoBERTa->RoBERTa-PreLayerNorm,Roberta->RobertaPreLayerNorm,roberta->roberta-prelayernorm +class RobertaPreLayerNormConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`RobertaPreLayerNormModel`]. It is + used to instantiate a RoBERTa-PreLayerNorm model according to the specified arguments, defining the model architecture. + Instantiating a configuration with the defaults will yield a similar configuration to that of the RoBERTa-PreLayerNorm + [andreasmadsen/efficient_mlm_m0.40](https://huggingface.co/andreasmadsen/efficient_mlm_m0.40) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + + Args: + vocab_size (`int`, *optional*, defaults to 50265): + Vocabulary size of the RoBERTa-PreLayerNorm model. Defines the number of different tokens that can be represented by the + `inputs_ids` passed when calling [`RobertaPreLayerNormModel`]. + hidden_size (`int`, *optional*, defaults to 768): + Dimensionality of the encoder layers and the pooler layer. + num_hidden_layers (`int`, *optional*, defaults to 12): + Number of hidden layers in the Transformer encoder. + num_attention_heads (`int`, *optional*, defaults to 12): + Number of attention heads for each attention layer in the Transformer encoder. + intermediate_size (`int`, *optional*, defaults to 3072): + Dimensionality of the "intermediate" (often named feed-forward) layer in the Transformer encoder. + hidden_act (`str` or `Callable`, *optional*, defaults to `"gelu"`): + The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`, + `"relu"`, `"silu"` and `"gelu_new"` are supported. + hidden_dropout_prob (`float`, *optional*, defaults to 0.1): + The dropout probability for all fully connected layers in the embeddings, encoder, and pooler. + attention_probs_dropout_prob (`float`, *optional*, defaults to 0.1): + The dropout ratio for the attention probabilities. + max_position_embeddings (`int`, *optional*, defaults to 512): + The maximum sequence length that this model might ever be used with. Typically set this to something large + just in case (e.g., 512 or 1024 or 2048). + type_vocab_size (`int`, *optional*, defaults to 2): + The vocabulary size of the `token_type_ids` passed when calling [`RobertaPreLayerNormModel`]. + initializer_range (`float`, *optional*, defaults to 0.02): + The standard deviation of the truncated_normal_initializer for initializing all weight matrices. + layer_norm_eps (`float`, *optional*, defaults to 1e-12): + The epsilon used by the layer normalization layers. + is_decoder (`bool`, *optional*, defaults to `False`): + Whether the model is used as a decoder or not. If `False`, the model is used as an encoder. + use_cache (`bool`, *optional*, defaults to `True`): + Whether or not the model should return the last key/values attentions (not used by all models). Only + relevant if `config.is_decoder=True`. + classifier_dropout (`float`, *optional*): + The dropout ratio for the classification head. + + Examples: + + ```python + >>> from transformers import RobertaPreLayerNormConfig, RobertaPreLayerNormModel + + >>> # Initializing a RoBERTa-PreLayerNorm configuration + >>> configuration = RobertaPreLayerNormConfig() + + >>> # Initializing a model (with random weights) from the configuration + >>> model = RobertaPreLayerNormModel(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "roberta-prelayernorm" + + def __init__( + self, + vocab_size=50265, + hidden_size=768, + num_hidden_layers=12, + num_attention_heads=12, + intermediate_size=3072, + hidden_act="gelu", + hidden_dropout_prob=0.1, + attention_probs_dropout_prob=0.1, + max_position_embeddings=512, + type_vocab_size=2, + initializer_range=0.02, + layer_norm_eps=1e-12, + pad_token_id=1, + bos_token_id=0, + eos_token_id=2, + use_cache=True, + classifier_dropout=None, + is_decoder=False, + add_cross_attention=False, + tie_word_embeddings=True, + **kwargs, + ): + super().__init__(**kwargs) + self.pad_token_id = pad_token_id + self.bos_token_id = bos_token_id + self.eos_token_id = eos_token_id + self.tie_word_embeddings = tie_word_embeddings + + self.is_decoder = is_decoder + self.add_cross_attention = add_cross_attention + self.vocab_size = vocab_size + self.hidden_size = hidden_size + self.num_hidden_layers = num_hidden_layers + self.num_attention_heads = num_attention_heads + self.hidden_act = hidden_act + self.intermediate_size = intermediate_size + self.hidden_dropout_prob = hidden_dropout_prob + self.attention_probs_dropout_prob = attention_probs_dropout_prob + self.max_position_embeddings = max_position_embeddings + self.type_vocab_size = type_vocab_size + self.initializer_range = initializer_range + self.layer_norm_eps = layer_norm_eps + self.use_cache = use_cache + self.classifier_dropout = classifier_dropout + + +__all__ = ["RobertaPreLayerNormConfig"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/roberta_prelayernorm/modeling_roberta_prelayernorm.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/roberta_prelayernorm/modeling_roberta_prelayernorm.py new file mode 100644 index 0000000000000000000000000000000000000000..9cbfa8b26292aeec639b892374ad35e3a43ade33 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/roberta_prelayernorm/modeling_roberta_prelayernorm.py @@ -0,0 +1,1342 @@ +# Copyright 2022 The Google AI Language Team Authors and The HuggingFace Inc. team. +# Copyright (c) 2018, NVIDIA CORPORATION. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""PyTorch RoBERTa-PreLayerNorm model.""" + +from collections.abc import Callable + +import torch +from torch import nn +from torch.nn import BCEWithLogitsLoss, CrossEntropyLoss, MSELoss + +from ... import initialization as init +from ...activations import ACT2FN, gelu +from ...cache_utils import Cache, DynamicCache, EncoderDecoderCache +from ...generation import GenerationMixin +from ...masking_utils import create_bidirectional_mask, create_causal_mask +from ...modeling_layers import GradientCheckpointingLayer +from ...modeling_outputs import ( + BaseModelOutputWithPastAndCrossAttentions, + BaseModelOutputWithPoolingAndCrossAttentions, + CausalLMOutputWithCrossAttentions, + MaskedLMOutput, + MultipleChoiceModelOutput, + QuestionAnsweringModelOutput, + SequenceClassifierOutput, + TokenClassifierOutput, +) +from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel +from ...processing_utils import Unpack +from ...pytorch_utils import apply_chunking_to_forward +from ...utils import TransformersKwargs, auto_docstring, logging +from ...utils.generic import can_return_tuple, merge_with_config_defaults +from ...utils.output_capturing import capture_outputs +from .configuration_roberta_prelayernorm import RobertaPreLayerNormConfig + + +logger = logging.get_logger(__name__) + + +# Copied from transformers.models.roberta.modeling_roberta.RobertaEmbeddings with Roberta->RobertaPreLayerNorm +class RobertaPreLayerNormEmbeddings(nn.Module): + """Construct the embeddings from word, position and token_type embeddings.""" + + def __init__(self, config): + super().__init__() + self.word_embeddings = nn.Embedding(config.vocab_size, config.hidden_size, padding_idx=config.pad_token_id) + self.token_type_embeddings = nn.Embedding(config.type_vocab_size, config.hidden_size) + + self.LayerNorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps) + self.dropout = nn.Dropout(config.hidden_dropout_prob) + # position_ids (1, len position emb) is contiguous in memory and exported when serialized + self.register_buffer( + "position_ids", torch.arange(config.max_position_embeddings).expand((1, -1)), persistent=False + ) + self.register_buffer( + "token_type_ids", torch.zeros(self.position_ids.size(), dtype=torch.long), persistent=False + ) + + self.padding_idx = config.pad_token_id + self.position_embeddings = nn.Embedding( + config.max_position_embeddings, config.hidden_size, padding_idx=self.padding_idx + ) + + def forward( + self, + input_ids: torch.LongTensor | None = None, + token_type_ids: torch.LongTensor | None = None, + position_ids: torch.LongTensor | None = None, + inputs_embeds: torch.FloatTensor | None = None, + past_key_values_length: int = 0, + ) -> torch.Tensor: + if position_ids is None: + if input_ids is not None: + # Create the position ids from the input token ids. Any padded tokens remain padded. + position_ids = self.create_position_ids_from_input_ids( + input_ids, self.padding_idx, past_key_values_length + ) + else: + position_ids = self.create_position_ids_from_inputs_embeds(inputs_embeds, self.padding_idx) + + if input_ids is not None: + input_shape = input_ids.size() + else: + input_shape = inputs_embeds.size()[:-1] + + batch_size, seq_length = input_shape + + # Setting the token_type_ids to the registered buffer in constructor where it is all zeros, which usually occurs + # when its auto-generated, registered buffer helps users when tracing the model without passing token_type_ids, solves + # issue #5664 + if token_type_ids is None: + if hasattr(self, "token_type_ids"): + # NOTE: We assume either pos ids to have bsz == 1 (broadcastable) or bsz == effective bsz (input_shape[0]) + buffered_token_type_ids = self.token_type_ids.expand(position_ids.shape[0], -1) + buffered_token_type_ids = torch.gather(buffered_token_type_ids, dim=1, index=position_ids) + token_type_ids = buffered_token_type_ids.expand(batch_size, seq_length) + else: + token_type_ids = torch.zeros(input_shape, dtype=torch.long, device=self.position_ids.device) + + if inputs_embeds is None: + inputs_embeds = self.word_embeddings(input_ids) + token_type_embeddings = self.token_type_embeddings(token_type_ids) + embeddings = inputs_embeds + token_type_embeddings + + position_embeddings = self.position_embeddings(position_ids) + embeddings = embeddings + position_embeddings + + embeddings = self.LayerNorm(embeddings) + embeddings = self.dropout(embeddings) + return embeddings + + @staticmethod + def create_position_ids_from_inputs_embeds(inputs_embeds, padding_idx): + """ + We are provided embeddings directly. We cannot infer which are padded so just generate sequential position ids. + + Args: + inputs_embeds: torch.Tensor + + Returns: torch.Tensor + """ + input_shape = inputs_embeds.size()[:-1] + sequence_length = input_shape[1] + + position_ids = torch.arange( + padding_idx + 1, sequence_length + padding_idx + 1, dtype=torch.long, device=inputs_embeds.device + ) + return position_ids.unsqueeze(0).expand(input_shape) + + @staticmethod + def create_position_ids_from_input_ids(input_ids, padding_idx, past_key_values_length=0): + """ + Replace non-padding symbols with their position numbers. Position numbers begin at padding_idx+1. Padding symbols + are ignored. This is modified from fairseq's `utils.make_positions`. + + Args: + x: torch.Tensor x: + + Returns: torch.Tensor + """ + # The series of casts and type-conversions here are carefully balanced to both work with ONNX export and XLA. + mask = input_ids.ne(padding_idx).int() + incremental_indices = (torch.cumsum(mask, dim=1).type_as(mask) + past_key_values_length) * mask + return incremental_indices.long() + padding_idx + + +# Copied from transformers.models.bert.modeling_bert.eager_attention_forward +def eager_attention_forward( + module: nn.Module, + query: torch.Tensor, + key: torch.Tensor, + value: torch.Tensor, + attention_mask: torch.Tensor | None, + scaling: float | None = None, + dropout: float = 0.0, + **kwargs: Unpack[TransformersKwargs], +): + if scaling is None: + scaling = query.size(-1) ** -0.5 + + # Take the dot product between "query" and "key" to get the raw attention scores. + attn_weights = torch.matmul(query, key.transpose(2, 3)) * scaling + + if attention_mask is not None: + attn_weights = attn_weights + attention_mask + + attn_weights = nn.functional.softmax(attn_weights, dim=-1) + attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training) + + attn_output = torch.matmul(attn_weights, value) + attn_output = attn_output.transpose(1, 2).contiguous() + + return attn_output, attn_weights + + +# Copied from transformers.models.bert.modeling_bert.BertSelfAttention with Bert->RobertaPreLayerNorm +class RobertaPreLayerNormSelfAttention(nn.Module): + def __init__(self, config, is_causal=False, layer_idx=None): + super().__init__() + if config.hidden_size % config.num_attention_heads != 0 and not hasattr(config, "embedding_size"): + raise ValueError( + f"The hidden size ({config.hidden_size}) is not a multiple of the number of attention " + f"heads ({config.num_attention_heads})" + ) + self.config = config + + self.num_attention_heads = config.num_attention_heads + self.attention_head_size = int(config.hidden_size / config.num_attention_heads) + self.all_head_size = self.num_attention_heads * self.attention_head_size + self.scaling = self.attention_head_size**-0.5 + + self.query = nn.Linear(config.hidden_size, self.all_head_size) + self.key = nn.Linear(config.hidden_size, self.all_head_size) + self.value = nn.Linear(config.hidden_size, self.all_head_size) + + self.dropout = nn.Dropout(config.attention_probs_dropout_prob) + + self.is_decoder = config.is_decoder + self.is_causal = is_causal + self.layer_idx = layer_idx + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.FloatTensor | None = None, + past_key_values: Cache | None = None, + cache_position: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor]: + input_shape = hidden_states.shape[:-1] + hidden_shape = (*input_shape, -1, self.attention_head_size) + + # get all proj + query_layer = self.query(hidden_states).view(*hidden_shape).transpose(1, 2) + key_layer = self.key(hidden_states).view(*hidden_shape).transpose(1, 2) + value_layer = self.value(hidden_states).view(*hidden_shape).transpose(1, 2) + + if past_key_values is not None: + # decoder-only bert can have a simple dynamic cache for example + current_past_key_values = past_key_values + if isinstance(past_key_values, EncoderDecoderCache): + current_past_key_values = past_key_values.self_attention_cache + + # save all key/value_layer to cache to be re-used for fast auto-regressive generation + key_layer, value_layer = current_past_key_values.update( + key_layer, + value_layer, + self.layer_idx, + {"cache_position": cache_position}, + ) + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, eager_attention_forward + ) + + attn_output, attn_weights = attention_interface( + self, + query_layer, + key_layer, + value_layer, + attention_mask, + dropout=0.0 if not self.training else self.dropout.p, + scaling=self.scaling, + **kwargs, + ) + attn_output = attn_output.reshape(*input_shape, -1).contiguous() + return attn_output, attn_weights + + +# Copied from transformers.models.bert.modeling_bert.BertCrossAttention with Bert->RobertaPreLayerNorm +class RobertaPreLayerNormCrossAttention(nn.Module): + def __init__(self, config, is_causal=False, layer_idx=None): + super().__init__() + if config.hidden_size % config.num_attention_heads != 0 and not hasattr(config, "embedding_size"): + raise ValueError( + f"The hidden size ({config.hidden_size}) is not a multiple of the number of attention " + f"heads ({config.num_attention_heads})" + ) + self.config = config + + self.num_attention_heads = config.num_attention_heads + self.attention_head_size = int(config.hidden_size / config.num_attention_heads) + self.all_head_size = self.num_attention_heads * self.attention_head_size + self.scaling = self.attention_head_size**-0.5 + + self.query = nn.Linear(config.hidden_size, self.all_head_size) + self.key = nn.Linear(config.hidden_size, self.all_head_size) + self.value = nn.Linear(config.hidden_size, self.all_head_size) + + self.dropout = nn.Dropout(config.attention_probs_dropout_prob) + + self.is_causal = is_causal + self.layer_idx = layer_idx + + def forward( + self, + hidden_states: torch.Tensor, + encoder_hidden_states: torch.FloatTensor | None = None, + attention_mask: torch.FloatTensor | None = None, + past_key_values: EncoderDecoderCache | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor]: + # determine input shapes + bsz, tgt_len = hidden_states.shape[:-1] + src_len = encoder_hidden_states.shape[1] + + q_input_shape = (bsz, tgt_len, -1, self.attention_head_size) + kv_input_shape = (bsz, src_len, -1, self.attention_head_size) + + # get query proj + query_layer = self.query(hidden_states).view(*q_input_shape).transpose(1, 2) + + is_updated = past_key_values.is_updated.get(self.layer_idx) if past_key_values is not None else False + if past_key_values is not None and is_updated: + # reuse k,v, cross_attentions + key_layer = past_key_values.cross_attention_cache.layers[self.layer_idx].keys + value_layer = past_key_values.cross_attention_cache.layers[self.layer_idx].values + else: + key_layer = self.key(encoder_hidden_states).view(*kv_input_shape).transpose(1, 2) + value_layer = self.value(encoder_hidden_states).view(*kv_input_shape).transpose(1, 2) + + if past_key_values is not None: + # save all states to the cache + key_layer, value_layer = past_key_values.cross_attention_cache.update( + key_layer, value_layer, self.layer_idx + ) + # set flag that curr layer for cross-attn is already updated so we can re-use in subsequent calls + past_key_values.is_updated[self.layer_idx] = True + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, eager_attention_forward + ) + + attn_output, attn_weights = attention_interface( + self, + query_layer, + key_layer, + value_layer, + attention_mask, + dropout=0.0 if not self.training else self.dropout.p, + scaling=self.scaling, + **kwargs, + ) + attn_output = attn_output.reshape(bsz, tgt_len, -1).contiguous() + return attn_output, attn_weights + + +class RobertaPreLayerNormSelfOutput(nn.Module): + def __init__(self, config): + super().__init__() + self.dense = nn.Linear(config.hidden_size, config.hidden_size) + self.dropout = nn.Dropout(config.hidden_dropout_prob) + + def forward(self, hidden_states: torch.Tensor, input_tensor: torch.Tensor) -> torch.Tensor: + hidden_states = self.dense(hidden_states) + hidden_states = self.dropout(hidden_states) + hidden_states = hidden_states + input_tensor + return hidden_states + + +class RobertaPreLayerNormAttention(nn.Module): + def __init__(self, config, is_causal=False, layer_idx=None, is_cross_attention=False): + super().__init__() + self.is_cross_attention = is_cross_attention + attention_class = RobertaPreLayerNormCrossAttention if is_cross_attention else RobertaPreLayerNormSelfAttention + self.self = attention_class(config, is_causal=is_causal, layer_idx=layer_idx) + self.output = RobertaPreLayerNormSelfOutput(config) + self.LayerNorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps) + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.FloatTensor | None = None, + encoder_hidden_states: torch.FloatTensor | None = None, + encoder_attention_mask: torch.FloatTensor | None = None, + past_key_values: tuple[tuple[torch.FloatTensor]] | None = None, + cache_position: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor]: + hidden_states_pre_layer_norm = self.LayerNorm(hidden_states) + attention_mask = attention_mask if not self.is_cross_attention else encoder_attention_mask + attention_output, attn_weights = self.self( + hidden_states_pre_layer_norm, + encoder_hidden_states=encoder_hidden_states, + attention_mask=attention_mask, + past_key_values=past_key_values, + cache_position=cache_position, + **kwargs, + ) + attention_output = self.output(attention_output, hidden_states) + return attention_output, attn_weights + + +class RobertaPreLayerNormIntermediate(nn.Module): + def __init__(self, config): + super().__init__() + self.LayerNorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps) + self.dense = nn.Linear(config.hidden_size, config.intermediate_size) + if isinstance(config.hidden_act, str): + self.intermediate_act_fn = ACT2FN[config.hidden_act] + else: + self.intermediate_act_fn = config.hidden_act + + def forward(self, hidden_states: torch.Tensor) -> torch.Tensor: + hidden_states = self.LayerNorm(hidden_states) + hidden_states = self.dense(hidden_states) + hidden_states = self.intermediate_act_fn(hidden_states) + return hidden_states + + +class RobertaPreLayerNormOutput(nn.Module): + def __init__(self, config): + super().__init__() + self.dense = nn.Linear(config.intermediate_size, config.hidden_size) + self.dropout = nn.Dropout(config.hidden_dropout_prob) + + def forward(self, hidden_states: torch.Tensor, input_tensor: torch.Tensor) -> torch.Tensor: + hidden_states = self.dense(hidden_states) + hidden_states = self.dropout(hidden_states) + hidden_states = hidden_states + input_tensor + return hidden_states + + +# Copied from transformers.models.bert.modeling_bert.BertLayer with Bert->RobertaPreLayerNorm +class RobertaPreLayerNormLayer(GradientCheckpointingLayer): + def __init__(self, config, layer_idx=None): + super().__init__() + self.chunk_size_feed_forward = config.chunk_size_feed_forward + self.seq_len_dim = 1 + self.attention = RobertaPreLayerNormAttention(config, is_causal=config.is_decoder, layer_idx=layer_idx) + self.is_decoder = config.is_decoder + self.add_cross_attention = config.add_cross_attention + if self.add_cross_attention: + if not self.is_decoder: + raise ValueError(f"{self} should be used as a decoder model if cross attention is added") + self.crossattention = RobertaPreLayerNormAttention( + config, + is_causal=False, + layer_idx=layer_idx, + is_cross_attention=True, + ) + self.intermediate = RobertaPreLayerNormIntermediate(config) + self.output = RobertaPreLayerNormOutput(config) + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.FloatTensor | None = None, + encoder_hidden_states: torch.FloatTensor | None = None, + encoder_attention_mask: torch.FloatTensor | None = None, + past_key_values: Cache | None = None, + cache_position: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor]: + self_attention_output, _ = self.attention( + hidden_states, + attention_mask, + past_key_values=past_key_values, + cache_position=cache_position, + **kwargs, + ) + attention_output = self_attention_output + + if self.is_decoder and encoder_hidden_states is not None: + if not hasattr(self, "crossattention"): + raise ValueError( + f"If `encoder_hidden_states` are passed, {self} has to be instantiated with cross-attention layers" + " by setting `config.add_cross_attention=True`" + ) + + cross_attention_output, _ = self.crossattention( + self_attention_output, + None, # attention_mask + encoder_hidden_states, + encoder_attention_mask, + past_key_values=past_key_values, + **kwargs, + ) + attention_output = cross_attention_output + + layer_output = apply_chunking_to_forward( + self.feed_forward_chunk, self.chunk_size_feed_forward, self.seq_len_dim, attention_output + ) + return layer_output + + def feed_forward_chunk(self, attention_output): + intermediate_output = self.intermediate(attention_output) + layer_output = self.output(intermediate_output, attention_output) + return layer_output + + +# Copied from transformers.models.bert.modeling_bert.BertEncoder with Bert->RobertaPreLayerNorm +class RobertaPreLayerNormEncoder(nn.Module): + def __init__(self, config): + super().__init__() + self.config = config + self.layer = nn.ModuleList( + [RobertaPreLayerNormLayer(config, layer_idx=i) for i in range(config.num_hidden_layers)] + ) + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.FloatTensor | None = None, + encoder_hidden_states: torch.FloatTensor | None = None, + encoder_attention_mask: torch.FloatTensor | None = None, + past_key_values: Cache | None = None, + use_cache: bool | None = None, + cache_position: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor] | BaseModelOutputWithPastAndCrossAttentions: + for i, layer_module in enumerate(self.layer): + hidden_states = layer_module( + hidden_states, + attention_mask, + encoder_hidden_states, # as a positional argument for gradient checkpointing + encoder_attention_mask=encoder_attention_mask, + past_key_values=past_key_values, + cache_position=cache_position, + **kwargs, + ) + + return BaseModelOutputWithPastAndCrossAttentions( + last_hidden_state=hidden_states, + past_key_values=past_key_values if use_cache else None, + ) + + +# Copied from transformers.models.bert.modeling_bert.BertPooler +class RobertaPreLayerNormPooler(nn.Module): + def __init__(self, config): + super().__init__() + self.dense = nn.Linear(config.hidden_size, config.hidden_size) + self.activation = nn.Tanh() + + def forward(self, hidden_states: torch.Tensor) -> torch.Tensor: + # We "pool" the model by simply taking the hidden state corresponding + # to the first token. + first_token_tensor = hidden_states[:, 0] + pooled_output = self.dense(first_token_tensor) + pooled_output = self.activation(pooled_output) + return pooled_output + + +@auto_docstring +class RobertaPreLayerNormPreTrainedModel(PreTrainedModel): + config_class = RobertaPreLayerNormConfig + base_model_prefix = "roberta_prelayernorm" + supports_gradient_checkpointing = True + _no_split_modules = [ + "RobertaPreLayerNormEmbeddings", + "RobertaPreLayerNormSelfAttention", + "RobertaPreLayerNormCrossAttention", + ] + _supports_flash_attn = True + _supports_sdpa = True + _supports_flex_attn = True + _supports_attention_backend = True + _can_record_outputs = { + "hidden_states": RobertaPreLayerNormLayer, + "attentions": RobertaPreLayerNormSelfAttention, + "cross_attentions": RobertaPreLayerNormCrossAttention, + } + + @torch.no_grad() + def _init_weights(self, module): + """Initialize the weights""" + super()._init_weights(module) + if isinstance(module, RobertaPreLayerNormLMHead): + init.zeros_(module.bias) + elif isinstance(module, RobertaPreLayerNormEmbeddings): + init.copy_(module.position_ids, torch.arange(module.position_ids.shape[-1]).expand((1, -1))) + init.zeros_(module.token_type_ids) + + +@auto_docstring( + custom_intro=""" + + The model can behave as an encoder (with only self-attention) as well as a decoder, in which case a layer of + cross-attention is added between the self-attention layers, following the architecture described in *Attention is + all you need*_ by Ashish Vaswani, Noam Shazeer, Niki Parmar, Jakob Uszkoreit, Llion Jones, Aidan N. Gomez, Lukasz + Kaiser and Illia Polosukhin. + + To behave as an decoder the model needs to be initialized with the `is_decoder` argument of the configuration set + to `True`. To be used in a Seq2Seq model, the model needs to initialized with both `is_decoder` argument and + `add_cross_attention` set to `True`; an `encoder_hidden_states` is then expected as an input to the forward pass. + + .. _*Attention is all you need*: https://huggingface.co/papers/1706.03762 + """ +) +class RobertaPreLayerNormModel(RobertaPreLayerNormPreTrainedModel): + def __init__(self, config, add_pooling_layer=True): + r""" + add_pooling_layer (bool, *optional*, defaults to `True`): + Whether to add a pooling layer + """ + super().__init__(config) + self.config = config + self.gradient_checkpointing = False + + self.embeddings = RobertaPreLayerNormEmbeddings(config) + self.encoder = RobertaPreLayerNormEncoder(config) + self.LayerNorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps) + + self.pooler = RobertaPreLayerNormPooler(config) if add_pooling_layer else None + + # Initialize weights and apply final processing + self.post_init() + + def get_input_embeddings(self): + return self.embeddings.word_embeddings + + def set_input_embeddings(self, value): + self.embeddings.word_embeddings = value + + @merge_with_config_defaults + @capture_outputs + @auto_docstring + def forward( + self, + input_ids: torch.Tensor | None = None, + attention_mask: torch.Tensor | None = None, + token_type_ids: torch.Tensor | None = None, + position_ids: torch.Tensor | None = None, + inputs_embeds: torch.Tensor | None = None, + encoder_hidden_states: torch.Tensor | None = None, + encoder_attention_mask: torch.Tensor | None = None, + past_key_values: list[torch.FloatTensor] | None = None, + use_cache: bool | None = None, + cache_position: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor] | BaseModelOutputWithPoolingAndCrossAttentions: + r""" + token_type_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Segment token indices to indicate first and second portions of the inputs. Indices are selected in `[0,1]`: + + - 0 corresponds to a *sentence A* token, + - 1 corresponds to a *sentence B* token. + This parameter can only be used when the model is initialized with `type_vocab_size` parameter with value + >= 2. All the value in this tensor should be always < type_vocab_size. + + [What are token type IDs?](../glossary#token-type-ids) + """ + if self.config.is_decoder: + use_cache = use_cache if use_cache is not None else self.config.use_cache + else: + use_cache = False + + if use_cache and past_key_values is None: + past_key_values = ( + EncoderDecoderCache(DynamicCache(config=self.config), DynamicCache(config=self.config)) + if encoder_hidden_states is not None or self.config.is_encoder_decoder + else DynamicCache(config=self.config) + ) + + if (input_ids is None) ^ (inputs_embeds is not None): + raise ValueError("You must specify exactly one of input_ids or inputs_embeds") + + if input_ids is not None: + device = input_ids.device + input_shape = input_ids.shape + else: + device = inputs_embeds.device + input_shape = inputs_embeds.shape[:-1] + + seq_length = input_shape[1] + past_key_values_length = past_key_values.get_seq_length() if past_key_values is not None else 0 + if cache_position is None: + cache_position = torch.arange(past_key_values_length, past_key_values_length + seq_length, device=device) + + embedding_output = self.embeddings( + input_ids=input_ids, + position_ids=position_ids, + token_type_ids=token_type_ids, + inputs_embeds=inputs_embeds, + past_key_values_length=past_key_values_length, + ) + + attention_mask, encoder_attention_mask = self._create_attention_masks( + attention_mask=attention_mask, + encoder_attention_mask=encoder_attention_mask, + embedding_output=embedding_output, + encoder_hidden_states=encoder_hidden_states, + cache_position=cache_position, + past_key_values=past_key_values, + ) + + encoder_outputs = self.encoder( + embedding_output, + attention_mask=attention_mask, + encoder_hidden_states=encoder_hidden_states, + encoder_attention_mask=encoder_attention_mask, + past_key_values=past_key_values, + use_cache=use_cache, + cache_position=cache_position, + position_ids=position_ids, + **kwargs, + ) + sequence_output = encoder_outputs[0] + sequence_output = self.LayerNorm(sequence_output) + pooled_output = self.pooler(sequence_output) if self.pooler is not None else None + + return BaseModelOutputWithPoolingAndCrossAttentions( + last_hidden_state=sequence_output, + pooler_output=pooled_output, + past_key_values=encoder_outputs.past_key_values, + ) + + # Copied from transformers.models.bert.modeling_bert.BertModel._create_attention_masks + def _create_attention_masks( + self, + attention_mask, + encoder_attention_mask, + embedding_output, + encoder_hidden_states, + cache_position, + past_key_values, + ): + if self.config.is_decoder: + attention_mask = create_causal_mask( + config=self.config, + inputs_embeds=embedding_output, + attention_mask=attention_mask, + cache_position=cache_position, + past_key_values=past_key_values, + ) + else: + attention_mask = create_bidirectional_mask( + config=self.config, + inputs_embeds=embedding_output, + attention_mask=attention_mask, + ) + + if encoder_attention_mask is not None: + encoder_attention_mask = create_bidirectional_mask( + config=self.config, + inputs_embeds=embedding_output, + attention_mask=encoder_attention_mask, + encoder_hidden_states=encoder_hidden_states, + ) + + return attention_mask, encoder_attention_mask + + +@auto_docstring( + custom_intro=""" + RoBERTa-PreLayerNorm Model with a `language modeling` head on top for CLM fine-tuning. + """ +) +# Copied from transformers.models.roberta.modeling_roberta.RobertaForCausalLM with FacebookAI/roberta-base->andreasmadsen/efficient_mlm_m0.40,ROBERTA->ROBERTA_PRELAYERNORM,Roberta->RobertaPreLayerNorm,roberta->roberta_prelayernorm, RobertaPreLayerNormTokenizer->RobertaTokenizer +class RobertaPreLayerNormForCausalLM(RobertaPreLayerNormPreTrainedModel, GenerationMixin): + _tied_weights_keys = { + "lm_head.decoder.weight": "roberta_prelayernorm.embeddings.word_embeddings.weight", + "lm_head.decoder.bias": "lm_head.bias", + } + + def __init__(self, config): + super().__init__(config) + + if not config.is_decoder: + logger.warning( + "If you want to use `RobertaPreLayerNormLMHeadModel` as a standalone, add `is_decoder=True.`" + ) + + self.roberta_prelayernorm = RobertaPreLayerNormModel(config, add_pooling_layer=False) + self.lm_head = RobertaPreLayerNormLMHead(config) + + # Initialize weights and apply final processing + self.post_init() + + def get_output_embeddings(self): + return self.lm_head.decoder + + def set_output_embeddings(self, new_embeddings): + self.lm_head.decoder = new_embeddings + + @can_return_tuple + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.FloatTensor | None = None, + token_type_ids: torch.LongTensor | None = None, + position_ids: torch.LongTensor | None = None, + inputs_embeds: torch.FloatTensor | None = None, + encoder_hidden_states: torch.FloatTensor | None = None, + encoder_attention_mask: torch.FloatTensor | None = None, + labels: torch.LongTensor | None = None, + past_key_values: tuple[tuple[torch.FloatTensor]] | None = None, + use_cache: bool | None = None, + cache_position: torch.Tensor | None = None, + logits_to_keep: int | torch.Tensor = 0, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor] | CausalLMOutputWithCrossAttentions: + r""" + token_type_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Segment token indices to indicate first and second portions of the inputs. Indices are selected in `[0,1]`: + + - 0 corresponds to a *sentence A* token, + - 1 corresponds to a *sentence B* token. + This parameter can only be used when the model is initialized with `type_vocab_size` parameter with value + >= 2. All the value in this tensor should be always < type_vocab_size. + + [What are token type IDs?](../glossary#token-type-ids) + labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Labels for computing the left-to-right language modeling loss (next word prediction). Indices should be in + `[-100, 0, ..., config.vocab_size]` (see `input_ids` docstring) Tokens with indices set to `-100` are + ignored (masked), the loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]` + + Example: + + ```python + >>> from transformers import AutoTokenizer, RobertaPreLayerNormForCausalLM, AutoConfig + >>> import torch + + >>> tokenizer = AutoTokenizer.from_pretrained("andreasmadsen/efficient_mlm_m0.40") + >>> config = AutoConfig.from_pretrained("andreasmadsen/efficient_mlm_m0.40") + >>> config.is_decoder = True + >>> model = RobertaPreLayerNormForCausalLM.from_pretrained("andreasmadsen/efficient_mlm_m0.40", config=config) + + >>> inputs = tokenizer("Hello, my dog is cute", return_tensors="pt") + >>> outputs = model(**inputs) + + >>> prediction_logits = outputs.logits + ```""" + if labels is not None: + use_cache = False + + outputs: BaseModelOutputWithPoolingAndCrossAttentions = self.roberta_prelayernorm( + input_ids, + attention_mask=attention_mask, + token_type_ids=token_type_ids, + position_ids=position_ids, + inputs_embeds=inputs_embeds, + encoder_hidden_states=encoder_hidden_states, + encoder_attention_mask=encoder_attention_mask, + past_key_values=past_key_values, + use_cache=use_cache, + cache_position=cache_position, + return_dict=True, + **kwargs, + ) + + hidden_states = outputs.last_hidden_state + # Only compute necessary logits, and do not upcast them to float if we are not computing the loss + slice_indices = slice(-logits_to_keep, None) if isinstance(logits_to_keep, int) else logits_to_keep + logits = self.lm_head(hidden_states[:, slice_indices, :]) + + loss = None + if labels is not None: + loss = self.loss_function(logits=logits, labels=labels, vocab_size=self.config.vocab_size, **kwargs) + + return CausalLMOutputWithCrossAttentions( + loss=loss, + logits=logits, + past_key_values=outputs.past_key_values, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + cross_attentions=outputs.cross_attentions, + ) + + +@auto_docstring( + custom_intro=""" + RoBERTa-PreLayerNorm Model with a `language modeling` head on top. + """ +) +class RobertaPreLayerNormForMaskedLM(RobertaPreLayerNormPreTrainedModel): + _tied_weights_keys = { + "lm_head.decoder.weight": "roberta_prelayernorm.embeddings.word_embeddings.weight", + "lm_head.decoder.bias": "lm_head.bias", + } + + # Copied from transformers.models.roberta.modeling_roberta.RobertaForMaskedLM.__init__ with ROBERTA->ROBERTA_PRELAYERNORM,Roberta->RobertaPreLayerNorm,roberta->roberta_prelayernorm + def __init__(self, config): + super().__init__(config) + + if config.is_decoder: + logger.warning( + "If you want to use `RobertaPreLayerNormForMaskedLM` make sure `config.is_decoder=False` for " + "bi-directional self-attention." + ) + + self.roberta_prelayernorm = RobertaPreLayerNormModel(config, add_pooling_layer=False) + self.lm_head = RobertaPreLayerNormLMHead(config) + + # Initialize weights and apply final processing + self.post_init() + + def get_output_embeddings(self): + return self.lm_head.decoder + + def set_output_embeddings(self, new_embeddings): + self.lm_head.decoder = new_embeddings + + @can_return_tuple + @auto_docstring + # Copied from transformers.models.roberta.modeling_roberta.RobertaForMaskedLM.forward with ROBERTA->ROBERTA_PRELAYERNORM,Roberta->RobertaPreLayerNorm,roberta->roberta_prelayernorm + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.FloatTensor | None = None, + token_type_ids: torch.LongTensor | None = None, + position_ids: torch.LongTensor | None = None, + inputs_embeds: torch.FloatTensor | None = None, + encoder_hidden_states: torch.FloatTensor | None = None, + encoder_attention_mask: torch.FloatTensor | None = None, + labels: torch.LongTensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor] | MaskedLMOutput: + r""" + token_type_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Segment token indices to indicate first and second portions of the inputs. Indices are selected in `[0,1]`: + + - 0 corresponds to a *sentence A* token, + - 1 corresponds to a *sentence B* token. + This parameter can only be used when the model is initialized with `type_vocab_size` parameter with value + >= 2. All the value in this tensor should be always < type_vocab_size. + + [What are token type IDs?](../glossary#token-type-ids) + labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Labels for computing the masked language modeling loss. Indices should be in `[-100, 0, ..., + config.vocab_size]` (see `input_ids` docstring) Tokens with indices set to `-100` are ignored (masked), the + loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]` + """ + outputs = self.roberta_prelayernorm( + input_ids, + attention_mask=attention_mask, + token_type_ids=token_type_ids, + position_ids=position_ids, + inputs_embeds=inputs_embeds, + encoder_hidden_states=encoder_hidden_states, + encoder_attention_mask=encoder_attention_mask, + return_dict=True, + **kwargs, + ) + sequence_output = outputs[0] + prediction_scores = self.lm_head(sequence_output) + + masked_lm_loss = None + if labels is not None: + # move labels to correct device + labels = labels.to(prediction_scores.device) + loss_fct = CrossEntropyLoss() + masked_lm_loss = loss_fct(prediction_scores.view(-1, self.config.vocab_size), labels.view(-1)) + + return MaskedLMOutput( + loss=masked_lm_loss, + logits=prediction_scores, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + ) + + +# Copied from transformers.models.roberta.modeling_roberta.RobertaLMHead with Roberta->RobertaPreLayerNorm +class RobertaPreLayerNormLMHead(nn.Module): + """RobertaPreLayerNorm Head for masked language modeling.""" + + def __init__(self, config): + super().__init__() + self.dense = nn.Linear(config.hidden_size, config.hidden_size) + self.layer_norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps) + + self.decoder = nn.Linear(config.hidden_size, config.vocab_size) + self.bias = nn.Parameter(torch.zeros(config.vocab_size)) + + def forward(self, features, **kwargs): + x = self.dense(features) + x = gelu(x) + x = self.layer_norm(x) + + # project back to size of vocabulary with bias + x = self.decoder(x) + + return x + + +@auto_docstring( + custom_intro=""" + RoBERTa-PreLayerNorm Model transformer with a sequence classification/regression head on top (a linear layer on top + of the pooled output) e.g. for GLUE tasks. + """ +) +class RobertaPreLayerNormForSequenceClassification(RobertaPreLayerNormPreTrainedModel): + def __init__(self, config): + super().__init__(config) + self.num_labels = config.num_labels + self.config = config + + self.roberta_prelayernorm = RobertaPreLayerNormModel(config, add_pooling_layer=False) + self.classifier = RobertaPreLayerNormClassificationHead(config) + + # Initialize weights and apply final processing + self.post_init() + + @can_return_tuple + @auto_docstring + # Copied from transformers.models.roberta.modeling_roberta.RobertaForSequenceClassification.forward with roberta->roberta_prelayernorm + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.FloatTensor | None = None, + token_type_ids: torch.LongTensor | None = None, + position_ids: torch.LongTensor | None = None, + inputs_embeds: torch.FloatTensor | None = None, + labels: torch.LongTensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor] | SequenceClassifierOutput: + r""" + token_type_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Segment token indices to indicate first and second portions of the inputs. Indices are selected in `[0,1]`: + + - 0 corresponds to a *sentence A* token, + - 1 corresponds to a *sentence B* token. + This parameter can only be used when the model is initialized with `type_vocab_size` parameter with value + >= 2. All the value in this tensor should be always < type_vocab_size. + + [What are token type IDs?](../glossary#token-type-ids) + labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*): + Labels for computing the sequence classification/regression loss. Indices should be in `[0, ..., + config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If + `config.num_labels > 1` a classification loss is computed (Cross-Entropy). + """ + outputs = self.roberta_prelayernorm( + input_ids, + attention_mask=attention_mask, + token_type_ids=token_type_ids, + position_ids=position_ids, + inputs_embeds=inputs_embeds, + return_dict=True, + **kwargs, + ) + sequence_output = outputs[0] + logits = self.classifier(sequence_output) + + loss = None + if labels is not None: + # move labels to correct device + labels = labels.to(logits.device) + if self.config.problem_type is None: + if self.num_labels == 1: + self.config.problem_type = "regression" + elif self.num_labels > 1 and (labels.dtype == torch.long or labels.dtype == torch.int): + self.config.problem_type = "single_label_classification" + else: + self.config.problem_type = "multi_label_classification" + + if self.config.problem_type == "regression": + loss_fct = MSELoss() + if self.num_labels == 1: + loss = loss_fct(logits.squeeze(), labels.squeeze()) + else: + loss = loss_fct(logits, labels) + elif self.config.problem_type == "single_label_classification": + loss_fct = CrossEntropyLoss() + loss = loss_fct(logits.view(-1, self.num_labels), labels.view(-1)) + elif self.config.problem_type == "multi_label_classification": + loss_fct = BCEWithLogitsLoss() + loss = loss_fct(logits, labels) + + return SequenceClassifierOutput( + loss=loss, + logits=logits, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + ) + + +@auto_docstring +# Copied from transformers.models.roberta.modeling_roberta.RobertaForMultipleChoice with ROBERTA->ROBERTA_PRELAYERNORM,Roberta->RobertaPreLayerNorm,roberta->roberta_prelayernorm +class RobertaPreLayerNormForMultipleChoice(RobertaPreLayerNormPreTrainedModel): + def __init__(self, config): + super().__init__(config) + + self.roberta_prelayernorm = RobertaPreLayerNormModel(config) + self.dropout = nn.Dropout(config.hidden_dropout_prob) + self.classifier = nn.Linear(config.hidden_size, 1) + + # Initialize weights and apply final processing + self.post_init() + + @can_return_tuple + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + token_type_ids: torch.LongTensor | None = None, + attention_mask: torch.FloatTensor | None = None, + labels: torch.LongTensor | None = None, + position_ids: torch.LongTensor | None = None, + inputs_embeds: torch.FloatTensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor] | MultipleChoiceModelOutput: + r""" + input_ids (`torch.LongTensor` of shape `(batch_size, num_choices, sequence_length)`): + Indices of input sequence tokens in the vocabulary. + + Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and + [`PreTrainedTokenizer.__call__`] for details. + + [What are input IDs?](../glossary#input-ids) + token_type_ids (`torch.LongTensor` of shape `(batch_size, num_choices, sequence_length)`, *optional*): + Segment token indices to indicate first and second portions of the inputs. Indices are selected in `[0,1]`: + + - 0 corresponds to a *sentence A* token, + - 1 corresponds to a *sentence B* token. + This parameter can only be used when the model is initialized with `type_vocab_size` parameter with value + >= 2. All the value in this tensor should be always < type_vocab_size. + + [What are token type IDs?](../glossary#token-type-ids) + labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*): + Labels for computing the multiple choice classification loss. Indices should be in `[0, ..., + num_choices-1]` where `num_choices` is the size of the second dimension of the input tensors. (See + `input_ids` above) + position_ids (`torch.LongTensor` of shape `(batch_size, num_choices, sequence_length)`, *optional*): + Indices of positions of each input sequence tokens in the position embeddings. Selected in the range `[0, + config.max_position_embeddings - 1]`. + + [What are position IDs?](../glossary#position-ids) + inputs_embeds (`torch.FloatTensor` of shape `(batch_size, num_choices, sequence_length, hidden_size)`, *optional*): + Optionally, instead of passing `input_ids` you can choose to directly pass an embedded representation. This + is useful if you want more control over how to convert `input_ids` indices into associated vectors than the + model's internal embedding lookup matrix. + """ + num_choices = input_ids.shape[1] if input_ids is not None else inputs_embeds.shape[1] + + flat_input_ids = input_ids.view(-1, input_ids.size(-1)) if input_ids is not None else None + flat_position_ids = position_ids.view(-1, position_ids.size(-1)) if position_ids is not None else None + flat_token_type_ids = token_type_ids.view(-1, token_type_ids.size(-1)) if token_type_ids is not None else None + flat_attention_mask = attention_mask.view(-1, attention_mask.size(-1)) if attention_mask is not None else None + flat_inputs_embeds = ( + inputs_embeds.view(-1, inputs_embeds.size(-2), inputs_embeds.size(-1)) + if inputs_embeds is not None + else None + ) + + outputs = self.roberta_prelayernorm( + flat_input_ids, + position_ids=flat_position_ids, + token_type_ids=flat_token_type_ids, + attention_mask=flat_attention_mask, + inputs_embeds=flat_inputs_embeds, + return_dict=True, + **kwargs, + ) + pooled_output = outputs[1] + + pooled_output = self.dropout(pooled_output) + logits = self.classifier(pooled_output) + reshaped_logits = logits.view(-1, num_choices) + + loss = None + if labels is not None: + # move labels to correct device + labels = labels.to(reshaped_logits.device) + loss_fct = CrossEntropyLoss() + loss = loss_fct(reshaped_logits, labels) + + return MultipleChoiceModelOutput( + loss=loss, + logits=reshaped_logits, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + ) + + +@auto_docstring +class RobertaPreLayerNormForTokenClassification(RobertaPreLayerNormPreTrainedModel): + def __init__(self, config): + super().__init__(config) + self.num_labels = config.num_labels + + self.roberta_prelayernorm = RobertaPreLayerNormModel(config, add_pooling_layer=False) + classifier_dropout = ( + config.classifier_dropout if config.classifier_dropout is not None else config.hidden_dropout_prob + ) + self.dropout = nn.Dropout(classifier_dropout) + self.classifier = nn.Linear(config.hidden_size, config.num_labels) + + # Initialize weights and apply final processing + self.post_init() + + @can_return_tuple + @auto_docstring + # Copied from transformers.models.roberta.modeling_roberta.RobertaForTokenClassification.forward with roberta->roberta_prelayernorm + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.FloatTensor | None = None, + token_type_ids: torch.LongTensor | None = None, + position_ids: torch.LongTensor | None = None, + inputs_embeds: torch.FloatTensor | None = None, + labels: torch.LongTensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor] | TokenClassifierOutput: + r""" + token_type_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Segment token indices to indicate first and second portions of the inputs. Indices are selected in `[0,1]`: + + - 0 corresponds to a *sentence A* token, + - 1 corresponds to a *sentence B* token. + This parameter can only be used when the model is initialized with `type_vocab_size` parameter with value + >= 2. All the value in this tensor should be always < type_vocab_size. + + [What are token type IDs?](../glossary#token-type-ids) + labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Labels for computing the token classification loss. Indices should be in `[0, ..., config.num_labels - 1]`. + """ + outputs = self.roberta_prelayernorm( + input_ids, + attention_mask=attention_mask, + token_type_ids=token_type_ids, + position_ids=position_ids, + inputs_embeds=inputs_embeds, + return_dict=True, + **kwargs, + ) + + sequence_output = outputs[0] + + sequence_output = self.dropout(sequence_output) + logits = self.classifier(sequence_output) + + loss = None + if labels is not None: + # move labels to correct device + labels = labels.to(logits.device) + loss_fct = CrossEntropyLoss() + loss = loss_fct(logits.view(-1, self.num_labels), labels.view(-1)) + + return TokenClassifierOutput( + loss=loss, + logits=logits, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + ) + + +# Copied from transformers.models.roberta.modeling_roberta.RobertaClassificationHead with Roberta->RobertaPreLayerNorm +class RobertaPreLayerNormClassificationHead(nn.Module): + """Head for sentence-level classification tasks.""" + + def __init__(self, config): + super().__init__() + self.dense = nn.Linear(config.hidden_size, config.hidden_size) + classifier_dropout = ( + config.classifier_dropout if config.classifier_dropout is not None else config.hidden_dropout_prob + ) + self.dropout = nn.Dropout(classifier_dropout) + self.out_proj = nn.Linear(config.hidden_size, config.num_labels) + + def forward(self, features, **kwargs): + x = features[:, 0, :] # take token (equiv. to [CLS]) + x = self.dropout(x) + x = self.dense(x) + x = torch.tanh(x) + x = self.dropout(x) + x = self.out_proj(x) + return x + + +@auto_docstring +class RobertaPreLayerNormForQuestionAnswering(RobertaPreLayerNormPreTrainedModel): + def __init__(self, config): + super().__init__(config) + self.num_labels = config.num_labels + + self.roberta_prelayernorm = RobertaPreLayerNormModel(config, add_pooling_layer=False) + self.qa_outputs = nn.Linear(config.hidden_size, config.num_labels) + + # Initialize weights and apply final processing + self.post_init() + + @can_return_tuple + @auto_docstring + # Copied from transformers.models.roberta.modeling_roberta.RobertaForQuestionAnswering.forward with roberta->roberta_prelayernorm + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.FloatTensor | None = None, + token_type_ids: torch.LongTensor | None = None, + position_ids: torch.LongTensor | None = None, + inputs_embeds: torch.FloatTensor | None = None, + start_positions: torch.LongTensor | None = None, + end_positions: torch.LongTensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor] | QuestionAnsweringModelOutput: + r""" + token_type_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Segment token indices to indicate first and second portions of the inputs. Indices are selected in `[0,1]`: + + - 0 corresponds to a *sentence A* token, + - 1 corresponds to a *sentence B* token. + This parameter can only be used when the model is initialized with `type_vocab_size` parameter with value + >= 2. All the value in this tensor should be always < type_vocab_size. + + [What are token type IDs?](../glossary#token-type-ids) + """ + outputs = self.roberta_prelayernorm( + input_ids, + attention_mask=attention_mask, + token_type_ids=token_type_ids, + position_ids=position_ids, + inputs_embeds=inputs_embeds, + return_dict=True, + **kwargs, + ) + + sequence_output = outputs[0] + + logits = self.qa_outputs(sequence_output) + start_logits, end_logits = logits.split(1, dim=-1) + start_logits = start_logits.squeeze(-1).contiguous() + end_logits = end_logits.squeeze(-1).contiguous() + + total_loss = None + if start_positions is not None and end_positions is not None: + # If we are on multi-GPU, split add a dimension + if len(start_positions.size()) > 1: + start_positions = start_positions.squeeze(-1) + if len(end_positions.size()) > 1: + end_positions = end_positions.squeeze(-1) + # sometimes the start/end positions are outside our model inputs, we ignore these terms + ignored_index = start_logits.size(1) + start_positions = start_positions.clamp(0, ignored_index) + end_positions = end_positions.clamp(0, ignored_index) + + loss_fct = CrossEntropyLoss(ignore_index=ignored_index) + start_loss = loss_fct(start_logits, start_positions) + end_loss = loss_fct(end_logits, end_positions) + total_loss = (start_loss + end_loss) / 2 + + return QuestionAnsweringModelOutput( + loss=total_loss, + start_logits=start_logits, + end_logits=end_logits, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + ) + + +__all__ = [ + "RobertaPreLayerNormForCausalLM", + "RobertaPreLayerNormForMaskedLM", + "RobertaPreLayerNormForMultipleChoice", + "RobertaPreLayerNormForQuestionAnswering", + "RobertaPreLayerNormForSequenceClassification", + "RobertaPreLayerNormForTokenClassification", + "RobertaPreLayerNormModel", + "RobertaPreLayerNormPreTrainedModel", +] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/roc_bert/__init__.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/roc_bert/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..eb847b03b75587df50ebb17140401da0be4dea22 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/roc_bert/__init__.py @@ -0,0 +1,28 @@ +# Copyright 2024 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from typing import TYPE_CHECKING + +from ...utils import _LazyModule +from ...utils.import_utils import define_import_structure + + +if TYPE_CHECKING: + from .configuration_roc_bert import * + from .modeling_roc_bert import * + from .tokenization_roc_bert import * +else: + import sys + + _file = globals()["__file__"] + sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__) diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/roc_bert/configuration_roc_bert.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/roc_bert/configuration_roc_bert.py new file mode 100644 index 0000000000000000000000000000000000000000..3e0822f5bfa4d719044a0c85d9e9a5cce1a60f6e --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/roc_bert/configuration_roc_bert.py @@ -0,0 +1,161 @@ +# Copyright 2022 WeChatAI and The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""RoCBert model configuration""" + +from ...configuration_utils import PreTrainedConfig +from ...utils import logging + + +logger = logging.get_logger(__name__) + + +class RoCBertConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`RoCBertModel`]. It is used to instantiate a + RoCBert model according to the specified arguments, defining the model architecture. Instantiating a configuration + with the defaults will yield a similar configuration to that of the RoCBert + [weiweishi/roc-bert-base-zh](https://huggingface.co/weiweishi/roc-bert-base-zh) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + + Args: + vocab_size (`int`, *optional*, defaults to 30522): + Vocabulary size of the RoCBert model. Defines the number of different tokens that can be represented by the + `inputs_ids` passed when calling [`RoCBertModel`]. + hidden_size (`int`, *optional*, defaults to 768): + Dimension of the encoder layers and the pooler layer. + num_hidden_layers (`int`, *optional*, defaults to 12): + Number of hidden layers in the Transformer encoder. + num_attention_heads (`int`, *optional*, defaults to 12): + Number of attention heads for each attention layer in the Transformer encoder. + intermediate_size (`int`, *optional*, defaults to 3072): + Dimension of the "intermediate" (i.e., feed-forward) layer in the Transformer encoder. + hidden_act (`str` or `function`, *optional*, defaults to `"gelu"`): + The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`, + `"relu"`, `"selu"` and `"gelu_new"` are supported. + hidden_dropout_prob (`float`, *optional*, defaults to 0.1): + The dropout probability for all fully connected layers in the embeddings, encoder, and pooler. + attention_probs_dropout_prob (`float`, *optional*, defaults to 0.1): + The dropout ratio for the attention probabilities. + max_position_embeddings (`int`, *optional*, defaults to 512): + The maximum sequence length that this model might ever be used with. Typically set this to something large + just in case (e.g., 512 or 1024 or 2048). + type_vocab_size (`int`, *optional*, defaults to 2): + The vocabulary size of the `token_type_ids` passed when calling [`RoCBertModel`]. + initializer_range (`float`, *optional*, defaults to 0.02): + The standard deviation of the truncated_normal_initializer for initializing all weight matrices. + layer_norm_eps (`float`, *optional*, defaults to 1e-12): + The epsilon used by the layer normalization layers. + is_decoder (`bool`, *optional*, defaults to `False`): + Whether the model is used as a decoder or not. If `False`, the model is used as an encoder. + use_cache (`bool`, *optional*, defaults to `True`): + Whether or not the model should return the last key/values attentions (not used by all models). Only + relevant if `config.is_decoder=True`. + classifier_dropout (`float`, *optional*): + The dropout ratio for the classification head. + enable_pronunciation (`bool`, *optional*, defaults to `True`): + Whether or not the model use pronunciation embed when training. + enable_shape (`bool`, *optional*, defaults to `True`): + Whether or not the model use shape embed when training. + pronunciation_embed_dim (`int`, *optional*, defaults to 768): + Dimension of the pronunciation_embed. + pronunciation_vocab_size (`int`, *optional*, defaults to 910): + Pronunciation Vocabulary size of the RoCBert model. Defines the number of different tokens that can be + represented by the `input_pronunciation_ids` passed when calling [`RoCBertModel`]. + shape_embed_dim (`int`, *optional*, defaults to 512): + Dimension of the shape_embed. + shape_vocab_size (`int`, *optional*, defaults to 24858): + Shape Vocabulary size of the RoCBert model. Defines the number of different tokens that can be represented + by the `input_shape_ids` passed when calling [`RoCBertModel`]. + concat_input (`bool`, *optional*, defaults to `True`): + Defines the way of merging the shape_embed, pronunciation_embed and word_embed, if the value is true, + output_embed = torch.cat((word_embed, shape_embed, pronunciation_embed), -1), else output_embed = + (word_embed + shape_embed + pronunciation_embed) / 3 + Example: + + ```python + >>> from transformers import RoCBertModel, RoCBertConfig + + >>> # Initializing a RoCBert weiweishi/roc-bert-base-zh style configuration + >>> configuration = RoCBertConfig() + + >>> # Initializing a model from the weiweishi/roc-bert-base-zh style configuration + >>> model = RoCBertModel(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "roc_bert" + + def __init__( + self, + vocab_size=30522, + hidden_size=768, + num_hidden_layers=12, + num_attention_heads=12, + intermediate_size=3072, + hidden_act="gelu", + hidden_dropout_prob=0.1, + attention_probs_dropout_prob=0.1, + max_position_embeddings=512, + type_vocab_size=2, + initializer_range=0.02, + layer_norm_eps=1e-12, + use_cache=True, + pad_token_id=0, + classifier_dropout=None, + enable_pronunciation=True, + enable_shape=True, + pronunciation_embed_dim=768, + pronunciation_vocab_size=910, + shape_embed_dim=512, + shape_vocab_size=24858, + concat_input=True, + is_decoder=False, + add_cross_attention=False, + tie_word_embeddings=True, + **kwargs, + ): + self.is_decoder = is_decoder + self.add_cross_attention = add_cross_attention + self.tie_word_embeddings = tie_word_embeddings + self.vocab_size = vocab_size + self.max_position_embeddings = max_position_embeddings + self.hidden_size = hidden_size + self.num_hidden_layers = num_hidden_layers + self.num_attention_heads = num_attention_heads + self.intermediate_size = intermediate_size + self.hidden_act = hidden_act + self.hidden_dropout_prob = hidden_dropout_prob + self.attention_probs_dropout_prob = attention_probs_dropout_prob + self.initializer_range = initializer_range + self.type_vocab_size = type_vocab_size + self.layer_norm_eps = layer_norm_eps + self.use_cache = use_cache + self.enable_pronunciation = enable_pronunciation + self.enable_shape = enable_shape + self.pronunciation_embed_dim = pronunciation_embed_dim + self.pronunciation_vocab_size = pronunciation_vocab_size + self.shape_embed_dim = shape_embed_dim + self.shape_vocab_size = shape_vocab_size + self.concat_input = concat_input + self.classifier_dropout = classifier_dropout + super().__init__(**kwargs) + self.pad_token_id = pad_token_id + + +__all__ = ["RoCBertConfig"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/roc_bert/modeling_roc_bert.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/roc_bert/modeling_roc_bert.py new file mode 100644 index 0000000000000000000000000000000000000000..d3111ebfdba437978f95e3885fb51c7840c5f65b --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/roc_bert/modeling_roc_bert.py @@ -0,0 +1,1690 @@ +# Copyright 2022 WeChatAI The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""PyTorch RoCBert model.""" + +from collections.abc import Callable + +import torch +from torch import nn +from torch.nn import BCEWithLogitsLoss, CrossEntropyLoss, MSELoss + +from ... import initialization as init +from ...activations import ACT2FN +from ...cache_utils import Cache, DynamicCache, EncoderDecoderCache +from ...generation import GenerationMixin +from ...masking_utils import create_bidirectional_mask, create_causal_mask +from ...modeling_layers import GradientCheckpointingLayer +from ...modeling_outputs import ( + BaseModelOutputWithPastAndCrossAttentions, + BaseModelOutputWithPoolingAndCrossAttentions, + CausalLMOutputWithCrossAttentions, + MaskedLMOutput, + MultipleChoiceModelOutput, + QuestionAnsweringModelOutput, + SequenceClassifierOutput, + TokenClassifierOutput, +) +from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel +from ...processing_utils import Unpack +from ...pytorch_utils import apply_chunking_to_forward +from ...utils import TransformersKwargs, auto_docstring, logging +from ...utils.generic import can_return_tuple, merge_with_config_defaults +from ...utils.output_capturing import capture_outputs +from .configuration_roc_bert import RoCBertConfig + + +logger = logging.get_logger(__name__) + + +class RoCBertEmbeddings(nn.Module): + """Construct the embeddings from word, position, shape, pronunciation and token_type embeddings.""" + + def __init__(self, config): + super().__init__() + self.word_embeddings = nn.Embedding(config.vocab_size, config.hidden_size, padding_idx=config.pad_token_id) + self.pronunciation_embed = nn.Embedding( + config.pronunciation_vocab_size, config.pronunciation_embed_dim, padding_idx=config.pad_token_id + ) + self.shape_embed = nn.Embedding( + config.shape_vocab_size, config.shape_embed_dim, padding_idx=config.pad_token_id + ) + self.position_embeddings = nn.Embedding(config.max_position_embeddings, config.hidden_size) + self.token_type_embeddings = nn.Embedding(config.type_vocab_size, config.hidden_size) + + self.enable_pronunciation = config.enable_pronunciation + self.enable_shape = config.enable_shape + + if config.concat_input: + input_dim = config.hidden_size + if self.enable_pronunciation: + pronunciation_dim = config.pronunciation_embed_dim + input_dim += pronunciation_dim + if self.enable_shape: + shape_dim = config.shape_embed_dim + input_dim += shape_dim + self.map_inputs_layer = torch.nn.Linear(input_dim, config.hidden_size) + else: + self.map_inputs_layer = None + + self.LayerNorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps) + self.dropout = nn.Dropout(config.hidden_dropout_prob) + + # position_ids (1, len position emb) is contiguous in memory and exported when serialized + self.register_buffer( + "position_ids", torch.arange(config.max_position_embeddings).expand((1, -1)), persistent=False + ) + self.register_buffer( + "token_type_ids", + torch.zeros(self.position_ids.size(), dtype=torch.long, device=self.position_ids.device), + persistent=False, + ) + + def forward( + self, + input_ids=None, + input_shape_ids=None, + input_pronunciation_ids=None, + token_type_ids=None, + position_ids=None, + inputs_embeds=None, + past_key_values_length=0, + ): + if input_ids is not None: + input_shape = input_ids.size() + else: + input_shape = inputs_embeds.size()[:-1] + + batch_size, seq_length = input_shape + + if position_ids is None: + position_ids = self.position_ids[:, past_key_values_length : seq_length + past_key_values_length] + + # Setting the token_type_ids to the registered buffer in constructor where it is all zeros, which usually occurs + # when its auto-generated, registered buffer helps users when tracing the model without passing token_type_ids, solves + # issue #5664 + if token_type_ids is None: + if hasattr(self, "token_type_ids"): + # NOTE: We assume either pos ids to have bsz == 1 (broadcastable) or bsz == effective bsz (input_shape[0]) + buffered_token_type_ids = self.token_type_ids.expand(position_ids.shape[0], -1) + buffered_token_type_ids = torch.gather(buffered_token_type_ids, dim=1, index=position_ids) + token_type_ids = buffered_token_type_ids.expand(batch_size, seq_length) + else: + token_type_ids = torch.zeros(input_shape, dtype=torch.long, device=self.position_ids.device) + + if self.map_inputs_layer is None: + if inputs_embeds is None: + inputs_embeds = self.word_embeddings(input_ids) + token_type_embeddings = self.token_type_embeddings(token_type_ids) + embeddings = inputs_embeds + token_type_embeddings + position_embeddings = self.position_embeddings(position_ids) + embeddings = embeddings + position_embeddings + embeddings = self.LayerNorm(embeddings) + embeddings = self.dropout(embeddings) + + denominator = 1 + embedding_in = torch.clone(embeddings) + if self.enable_shape and input_shape_ids is not None: + embedding_shape = self.shape_embed(input_shape_ids) + embedding_in += embedding_shape + denominator += 1 + if self.enable_pronunciation and input_pronunciation_ids is not None: + embedding_pronunciation = self.pronunciation_embed(input_pronunciation_ids) + embedding_in += embedding_pronunciation + denominator += 1 + + embedding_in /= denominator + return embedding_in + else: + if inputs_embeds is None: + inputs_embeds = self.word_embeddings(input_ids) # embedding_word + device = inputs_embeds.device + + embedding_in = torch.clone(inputs_embeds) + if self.enable_shape: + if input_shape_ids is None: + input_shape_ids = torch.zeros(input_shape, dtype=torch.long, device=device) + embedding_shape = self.shape_embed(input_shape_ids) + embedding_in = torch.cat((embedding_in, embedding_shape), -1) + if self.enable_pronunciation: + if input_pronunciation_ids is None: + input_pronunciation_ids = torch.zeros(input_shape, dtype=torch.long, device=device) + embedding_pronunciation = self.pronunciation_embed(input_pronunciation_ids) + embedding_in = torch.cat((embedding_in, embedding_pronunciation), -1) + + embedding_in = self.map_inputs_layer(embedding_in) # batch_size * seq_len * hidden_dim + + token_type_embeddings = self.token_type_embeddings(token_type_ids) + embedding_in += token_type_embeddings + position_embeddings = self.position_embeddings(position_ids) + embedding_in += position_embeddings + + embedding_in = self.LayerNorm(embedding_in) + embedding_in = self.dropout(embedding_in) + return embedding_in + + +# Copied from transformers.models.bert.modeling_bert.eager_attention_forward +def eager_attention_forward( + module: nn.Module, + query: torch.Tensor, + key: torch.Tensor, + value: torch.Tensor, + attention_mask: torch.Tensor | None, + scaling: float | None = None, + dropout: float = 0.0, + **kwargs: Unpack[TransformersKwargs], +): + if scaling is None: + scaling = query.size(-1) ** -0.5 + + # Take the dot product between "query" and "key" to get the raw attention scores. + attn_weights = torch.matmul(query, key.transpose(2, 3)) * scaling + + if attention_mask is not None: + attn_weights = attn_weights + attention_mask + + attn_weights = nn.functional.softmax(attn_weights, dim=-1) + attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training) + + attn_output = torch.matmul(attn_weights, value) + attn_output = attn_output.transpose(1, 2).contiguous() + + return attn_output, attn_weights + + +# Copied from transformers.models.bert.modeling_bert.BertSelfAttention with Bert->RoCBert +class RoCBertSelfAttention(nn.Module): + def __init__(self, config, is_causal=False, layer_idx=None): + super().__init__() + if config.hidden_size % config.num_attention_heads != 0 and not hasattr(config, "embedding_size"): + raise ValueError( + f"The hidden size ({config.hidden_size}) is not a multiple of the number of attention " + f"heads ({config.num_attention_heads})" + ) + self.config = config + + self.num_attention_heads = config.num_attention_heads + self.attention_head_size = int(config.hidden_size / config.num_attention_heads) + self.all_head_size = self.num_attention_heads * self.attention_head_size + self.scaling = self.attention_head_size**-0.5 + + self.query = nn.Linear(config.hidden_size, self.all_head_size) + self.key = nn.Linear(config.hidden_size, self.all_head_size) + self.value = nn.Linear(config.hidden_size, self.all_head_size) + + self.dropout = nn.Dropout(config.attention_probs_dropout_prob) + + self.is_decoder = config.is_decoder + self.is_causal = is_causal + self.layer_idx = layer_idx + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.FloatTensor | None = None, + past_key_values: Cache | None = None, + cache_position: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor]: + input_shape = hidden_states.shape[:-1] + hidden_shape = (*input_shape, -1, self.attention_head_size) + + # get all proj + query_layer = self.query(hidden_states).view(*hidden_shape).transpose(1, 2) + key_layer = self.key(hidden_states).view(*hidden_shape).transpose(1, 2) + value_layer = self.value(hidden_states).view(*hidden_shape).transpose(1, 2) + + if past_key_values is not None: + # decoder-only bert can have a simple dynamic cache for example + current_past_key_values = past_key_values + if isinstance(past_key_values, EncoderDecoderCache): + current_past_key_values = past_key_values.self_attention_cache + + # save all key/value_layer to cache to be re-used for fast auto-regressive generation + key_layer, value_layer = current_past_key_values.update( + key_layer, + value_layer, + self.layer_idx, + {"cache_position": cache_position}, + ) + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, eager_attention_forward + ) + + attn_output, attn_weights = attention_interface( + self, + query_layer, + key_layer, + value_layer, + attention_mask, + dropout=0.0 if not self.training else self.dropout.p, + scaling=self.scaling, + **kwargs, + ) + attn_output = attn_output.reshape(*input_shape, -1).contiguous() + return attn_output, attn_weights + + +# Copied from transformers.models.bert.modeling_bert.BertCrossAttention with Bert->RoCBert +class RoCBertCrossAttention(nn.Module): + def __init__(self, config, is_causal=False, layer_idx=None): + super().__init__() + if config.hidden_size % config.num_attention_heads != 0 and not hasattr(config, "embedding_size"): + raise ValueError( + f"The hidden size ({config.hidden_size}) is not a multiple of the number of attention " + f"heads ({config.num_attention_heads})" + ) + self.config = config + + self.num_attention_heads = config.num_attention_heads + self.attention_head_size = int(config.hidden_size / config.num_attention_heads) + self.all_head_size = self.num_attention_heads * self.attention_head_size + self.scaling = self.attention_head_size**-0.5 + + self.query = nn.Linear(config.hidden_size, self.all_head_size) + self.key = nn.Linear(config.hidden_size, self.all_head_size) + self.value = nn.Linear(config.hidden_size, self.all_head_size) + + self.dropout = nn.Dropout(config.attention_probs_dropout_prob) + + self.is_causal = is_causal + self.layer_idx = layer_idx + + def forward( + self, + hidden_states: torch.Tensor, + encoder_hidden_states: torch.FloatTensor | None = None, + attention_mask: torch.FloatTensor | None = None, + past_key_values: EncoderDecoderCache | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor]: + # determine input shapes + bsz, tgt_len = hidden_states.shape[:-1] + src_len = encoder_hidden_states.shape[1] + + q_input_shape = (bsz, tgt_len, -1, self.attention_head_size) + kv_input_shape = (bsz, src_len, -1, self.attention_head_size) + + # get query proj + query_layer = self.query(hidden_states).view(*q_input_shape).transpose(1, 2) + + is_updated = past_key_values.is_updated.get(self.layer_idx) if past_key_values is not None else False + if past_key_values is not None and is_updated: + # reuse k,v, cross_attentions + key_layer = past_key_values.cross_attention_cache.layers[self.layer_idx].keys + value_layer = past_key_values.cross_attention_cache.layers[self.layer_idx].values + else: + key_layer = self.key(encoder_hidden_states).view(*kv_input_shape).transpose(1, 2) + value_layer = self.value(encoder_hidden_states).view(*kv_input_shape).transpose(1, 2) + + if past_key_values is not None: + # save all states to the cache + key_layer, value_layer = past_key_values.cross_attention_cache.update( + key_layer, value_layer, self.layer_idx + ) + # set flag that curr layer for cross-attn is already updated so we can re-use in subsequent calls + past_key_values.is_updated[self.layer_idx] = True + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, eager_attention_forward + ) + + attn_output, attn_weights = attention_interface( + self, + query_layer, + key_layer, + value_layer, + attention_mask, + dropout=0.0 if not self.training else self.dropout.p, + scaling=self.scaling, + **kwargs, + ) + attn_output = attn_output.reshape(bsz, tgt_len, -1).contiguous() + return attn_output, attn_weights + + +# Copied from transformers.models.bert.modeling_bert.BertSelfOutput with Bert->RoCBert +class RoCBertSelfOutput(nn.Module): + def __init__(self, config): + super().__init__() + self.dense = nn.Linear(config.hidden_size, config.hidden_size) + self.LayerNorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps) + self.dropout = nn.Dropout(config.hidden_dropout_prob) + + def forward(self, hidden_states: torch.Tensor, input_tensor: torch.Tensor) -> torch.Tensor: + hidden_states = self.dense(hidden_states) + hidden_states = self.dropout(hidden_states) + hidden_states = self.LayerNorm(hidden_states + input_tensor) + return hidden_states + + +# Copied from transformers.models.bert.modeling_bert.BertAttention with Bert->RoCBert,BERT->ROC_BERT +class RoCBertAttention(nn.Module): + def __init__(self, config, is_causal=False, layer_idx=None, is_cross_attention=False): + super().__init__() + self.is_cross_attention = is_cross_attention + attention_class = RoCBertCrossAttention if is_cross_attention else RoCBertSelfAttention + self.self = attention_class(config, is_causal=is_causal, layer_idx=layer_idx) + self.output = RoCBertSelfOutput(config) + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.FloatTensor | None = None, + encoder_hidden_states: torch.FloatTensor | None = None, + encoder_attention_mask: torch.FloatTensor | None = None, + past_key_values: Cache | None = None, + cache_position: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor]: + attention_mask = attention_mask if not self.is_cross_attention else encoder_attention_mask + attention_output, attn_weights = self.self( + hidden_states, + encoder_hidden_states=encoder_hidden_states, + attention_mask=attention_mask, + past_key_values=past_key_values, + cache_position=cache_position, + **kwargs, + ) + attention_output = self.output(attention_output, hidden_states) + return attention_output, attn_weights + + +# Copied from transformers.models.bert.modeling_bert.BertIntermediate with Bert->RoCBert +class RoCBertIntermediate(nn.Module): + def __init__(self, config): + super().__init__() + self.dense = nn.Linear(config.hidden_size, config.intermediate_size) + if isinstance(config.hidden_act, str): + self.intermediate_act_fn = ACT2FN[config.hidden_act] + else: + self.intermediate_act_fn = config.hidden_act + + def forward(self, hidden_states: torch.Tensor) -> torch.Tensor: + hidden_states = self.dense(hidden_states) + hidden_states = self.intermediate_act_fn(hidden_states) + return hidden_states + + +# Copied from transformers.models.bert.modeling_bert.BertOutput with Bert->RoCBert +class RoCBertOutput(nn.Module): + def __init__(self, config): + super().__init__() + self.dense = nn.Linear(config.intermediate_size, config.hidden_size) + self.LayerNorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps) + self.dropout = nn.Dropout(config.hidden_dropout_prob) + + def forward(self, hidden_states: torch.Tensor, input_tensor: torch.Tensor) -> torch.Tensor: + hidden_states = self.dense(hidden_states) + hidden_states = self.dropout(hidden_states) + hidden_states = self.LayerNorm(hidden_states + input_tensor) + return hidden_states + + +# Copied from transformers.models.bert.modeling_bert.BertLayer with Bert->RoCBert +class RoCBertLayer(GradientCheckpointingLayer): + def __init__(self, config, layer_idx=None): + super().__init__() + self.chunk_size_feed_forward = config.chunk_size_feed_forward + self.seq_len_dim = 1 + self.attention = RoCBertAttention(config, is_causal=config.is_decoder, layer_idx=layer_idx) + self.is_decoder = config.is_decoder + self.add_cross_attention = config.add_cross_attention + if self.add_cross_attention: + if not self.is_decoder: + raise ValueError(f"{self} should be used as a decoder model if cross attention is added") + self.crossattention = RoCBertAttention( + config, + is_causal=False, + layer_idx=layer_idx, + is_cross_attention=True, + ) + self.intermediate = RoCBertIntermediate(config) + self.output = RoCBertOutput(config) + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.FloatTensor | None = None, + encoder_hidden_states: torch.FloatTensor | None = None, + encoder_attention_mask: torch.FloatTensor | None = None, + past_key_values: Cache | None = None, + cache_position: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor]: + self_attention_output, _ = self.attention( + hidden_states, + attention_mask, + past_key_values=past_key_values, + cache_position=cache_position, + **kwargs, + ) + attention_output = self_attention_output + + if self.is_decoder and encoder_hidden_states is not None: + if not hasattr(self, "crossattention"): + raise ValueError( + f"If `encoder_hidden_states` are passed, {self} has to be instantiated with cross-attention layers" + " by setting `config.add_cross_attention=True`" + ) + + cross_attention_output, _ = self.crossattention( + self_attention_output, + None, # attention_mask + encoder_hidden_states, + encoder_attention_mask, + past_key_values=past_key_values, + **kwargs, + ) + attention_output = cross_attention_output + + layer_output = apply_chunking_to_forward( + self.feed_forward_chunk, self.chunk_size_feed_forward, self.seq_len_dim, attention_output + ) + return layer_output + + def feed_forward_chunk(self, attention_output): + intermediate_output = self.intermediate(attention_output) + layer_output = self.output(intermediate_output, attention_output) + return layer_output + + +# Copied from transformers.models.bert.modeling_bert.BertEncoder with Bert->RoCBert +class RoCBertEncoder(nn.Module): + def __init__(self, config): + super().__init__() + self.config = config + self.layer = nn.ModuleList([RoCBertLayer(config, layer_idx=i) for i in range(config.num_hidden_layers)]) + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.FloatTensor | None = None, + encoder_hidden_states: torch.FloatTensor | None = None, + encoder_attention_mask: torch.FloatTensor | None = None, + past_key_values: Cache | None = None, + use_cache: bool | None = None, + cache_position: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor] | BaseModelOutputWithPastAndCrossAttentions: + for i, layer_module in enumerate(self.layer): + hidden_states = layer_module( + hidden_states, + attention_mask, + encoder_hidden_states, # as a positional argument for gradient checkpointing + encoder_attention_mask=encoder_attention_mask, + past_key_values=past_key_values, + cache_position=cache_position, + **kwargs, + ) + + return BaseModelOutputWithPastAndCrossAttentions( + last_hidden_state=hidden_states, + past_key_values=past_key_values if use_cache else None, + ) + + +# Copied from transformers.models.bert.modeling_bert.BertPooler with Bert->RoCBert +class RoCBertPooler(nn.Module): + def __init__(self, config): + super().__init__() + self.dense = nn.Linear(config.hidden_size, config.hidden_size) + self.activation = nn.Tanh() + + def forward(self, hidden_states: torch.Tensor) -> torch.Tensor: + # We "pool" the model by simply taking the hidden state corresponding + # to the first token. + first_token_tensor = hidden_states[:, 0] + pooled_output = self.dense(first_token_tensor) + pooled_output = self.activation(pooled_output) + return pooled_output + + +# Copied from transformers.models.bert.modeling_bert.BertPredictionHeadTransform with Bert->RoCBert +class RoCBertPredictionHeadTransform(nn.Module): + def __init__(self, config): + super().__init__() + self.dense = nn.Linear(config.hidden_size, config.hidden_size) + if isinstance(config.hidden_act, str): + self.transform_act_fn = ACT2FN[config.hidden_act] + else: + self.transform_act_fn = config.hidden_act + self.LayerNorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps) + + def forward(self, hidden_states: torch.Tensor) -> torch.Tensor: + hidden_states = self.dense(hidden_states) + hidden_states = self.transform_act_fn(hidden_states) + hidden_states = self.LayerNorm(hidden_states) + return hidden_states + + +# Copied from transformers.models.bert.modeling_bert.BertLMPredictionHead with Bert->RoCBert +class RoCBertLMPredictionHead(nn.Module): + def __init__(self, config): + super().__init__() + self.transform = RoCBertPredictionHeadTransform(config) + + # The output weights are the same as the input embeddings, but there is + # an output-only bias for each token. + self.decoder = nn.Linear(config.hidden_size, config.vocab_size, bias=True) + self.bias = nn.Parameter(torch.zeros(config.vocab_size)) + + def forward(self, hidden_states): + hidden_states = self.transform(hidden_states) + hidden_states = self.decoder(hidden_states) + return hidden_states + + +# Copied from transformers.models.bert.modeling_bert.BertOnlyMLMHead with Bert->RoCBert +class RoCBertOnlyMLMHead(nn.Module): + def __init__(self, config): + super().__init__() + self.predictions = RoCBertLMPredictionHead(config) + + def forward(self, sequence_output: torch.Tensor) -> torch.Tensor: + prediction_scores = self.predictions(sequence_output) + return prediction_scores + + +@auto_docstring +class RoCBertPreTrainedModel(PreTrainedModel): + config_class = RoCBertConfig + base_model_prefix = "roc_bert" + supports_gradient_checkpointing = True + _supports_flash_attn = True + _supports_sdpa = True + _supports_flex_attn = True + _supports_attention_backend = True + _can_record_outputs = { + "hidden_states": RoCBertLayer, + "attentions": RoCBertSelfAttention, + "cross_attentions": RoCBertCrossAttention, + } + + @torch.no_grad() + def _init_weights(self, module): + """Initialize the weights""" + super()._init_weights(module) + if isinstance(module, RoCBertLMPredictionHead): + init.zeros_(module.bias) + elif isinstance(module, RoCBertEmbeddings): + init.copy_(module.position_ids, torch.arange(module.position_ids.shape[-1]).expand((1, -1))) + init.zeros_(module.token_type_ids) + + +@auto_docstring( + custom_intro=""" + + The model can behave as an encoder (with only self-attention) as well as a decoder, in which case a layer of + cross-attention is added between the self-attention layers, following the architecture described in [Attention is + all you need](https://huggingface.co/papers/1706.03762) by Ashish Vaswani, Noam Shazeer, Niki Parmar, Jakob Uszkoreit, + Llion Jones, Aidan N. Gomez, Lukasz Kaiser and Illia Polosukhin. + + To behave as an decoder the model needs to be initialized with the `is_decoder` argument of the configuration set + to `True`. To be used in a Seq2Seq model, the model needs to be initialized with both `is_decoder` argument and + `add_cross_attention` set to `True`; an `encoder_hidden_states` is then expected as an input to the forward pass. + """ +) +class RoCBertModel(RoCBertPreTrainedModel): + def __init__(self, config, add_pooling_layer=True): + r""" + add_pooling_layer (bool, *optional*, defaults to `True`): + Whether to add a pooling layer + """ + super().__init__(config) + self.config = config + self.gradient_checkpointing = False + + self.embeddings = RoCBertEmbeddings(config) + self.encoder = RoCBertEncoder(config) + + self.pooler = RoCBertPooler(config) if add_pooling_layer else None + + # Initialize weights and apply final processing + self.post_init() + + # Copied from transformers.models.bert.modeling_bert.BertModel.get_input_embeddings + def get_input_embeddings(self): + return self.embeddings.word_embeddings + + # Copied from transformers.models.bert.modeling_bert.BertModel.set_input_embeddings + def set_input_embeddings(self, value): + self.embeddings.word_embeddings = value + + def get_pronunciation_embeddings(self): + return self.embeddings.pronunciation_embed + + def set_pronunciation_embeddings(self, value): + self.embeddings.pronunciation_embed = value + + def get_shape_embeddings(self): + return self.embeddings.shape_embed + + def set_shape_embeddings(self, value): + self.embeddings.shape_embed = value + + @merge_with_config_defaults + @capture_outputs + @auto_docstring + def forward( + self, + input_ids: torch.Tensor | None = None, + input_shape_ids: torch.Tensor | None = None, + input_pronunciation_ids: torch.Tensor | None = None, + attention_mask: torch.Tensor | None = None, + token_type_ids: torch.Tensor | None = None, + position_ids: torch.Tensor | None = None, + inputs_embeds: torch.Tensor | None = None, + encoder_hidden_states: torch.Tensor | None = None, + encoder_attention_mask: torch.Tensor | None = None, + past_key_values: Cache | None = None, + use_cache: bool | None = None, + cache_position: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor] | BaseModelOutputWithPoolingAndCrossAttentions: + r""" + input_shape_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`): + Indices of input sequence tokens in the shape vocabulary. + + Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and + [`PreTrainedTokenizer.__call__`] for details. + + [What are input IDs?](../glossary#input_shape_ids) + input_pronunciation_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`): + Indices of input sequence tokens in the pronunciation vocabulary. + + Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and + [`PreTrainedTokenizer.__call__`] for details. + + [What are input IDs?](../glossary#input_pronunciation_ids) + """ + if self.config.is_decoder: + use_cache = use_cache if use_cache is not None else self.config.use_cache + else: + use_cache = False + + if use_cache and past_key_values is None: + past_key_values = EncoderDecoderCache(DynamicCache(config=self.config), DynamicCache(config=self.config)) + + if (input_ids is None) ^ (inputs_embeds is not None): + raise ValueError("You must specify exactly one of input_ids or inputs_embeds") + + if input_ids is not None: + device = input_ids.device + input_shape = input_ids.shape + else: + device = inputs_embeds.device + input_shape = inputs_embeds.shape[:-1] + + seq_length = input_shape[1] + past_key_values_length = past_key_values.get_seq_length() if past_key_values is not None else 0 + if cache_position is None: + cache_position = torch.arange(past_key_values_length, past_key_values_length + seq_length, device=device) + + embedding_output = self.embeddings( + input_ids=input_ids, + input_shape_ids=input_shape_ids, + input_pronunciation_ids=input_pronunciation_ids, + position_ids=position_ids, + token_type_ids=token_type_ids, + inputs_embeds=inputs_embeds, + past_key_values_length=past_key_values_length, + ) + + attention_mask, encoder_attention_mask = self._create_attention_masks( + attention_mask=attention_mask, + encoder_attention_mask=encoder_attention_mask, + embedding_output=embedding_output, + encoder_hidden_states=encoder_hidden_states, + cache_position=cache_position, + past_key_values=past_key_values, + ) + + encoder_outputs = self.encoder( + embedding_output, + attention_mask=attention_mask, + encoder_hidden_states=encoder_hidden_states, + encoder_attention_mask=encoder_attention_mask, + past_key_values=past_key_values, + use_cache=use_cache, + cache_position=cache_position, + position_ids=position_ids, + **kwargs, + ) + sequence_output = encoder_outputs[0] + pooled_output = self.pooler(sequence_output) if self.pooler is not None else None + + return BaseModelOutputWithPoolingAndCrossAttentions( + last_hidden_state=sequence_output, + pooler_output=pooled_output, + past_key_values=encoder_outputs.past_key_values, + ) + + # Copied from transformers.models.bert.modeling_bert.BertModel._create_attention_masks + def _create_attention_masks( + self, + attention_mask, + encoder_attention_mask, + embedding_output, + encoder_hidden_states, + cache_position, + past_key_values, + ): + if self.config.is_decoder: + attention_mask = create_causal_mask( + config=self.config, + inputs_embeds=embedding_output, + attention_mask=attention_mask, + cache_position=cache_position, + past_key_values=past_key_values, + ) + else: + attention_mask = create_bidirectional_mask( + config=self.config, + inputs_embeds=embedding_output, + attention_mask=attention_mask, + ) + + if encoder_attention_mask is not None: + encoder_attention_mask = create_bidirectional_mask( + config=self.config, + inputs_embeds=embedding_output, + attention_mask=encoder_attention_mask, + encoder_hidden_states=encoder_hidden_states, + ) + + return attention_mask, encoder_attention_mask + + +@auto_docstring( + custom_intro=""" + RoCBert Model with contrastive loss and masked_lm_loss during the pretraining. + """ +) +class RoCBertForPreTraining(RoCBertPreTrainedModel): + _tied_weights_keys = { + "cls.predictions.decoder.bias": "cls.predictions.bias", + "cls.predictions.decoder.weight": "roc_bert.embeddings.word_embeddings.weight", + } + + def __init__(self, config): + super().__init__(config) + + self.roc_bert = RoCBertModel(config) + self.cls = RoCBertOnlyMLMHead(config) + + # Initialize weights and apply final processing + self.post_init() + + # Copied from transformers.models.bert.modeling_bert.BertForPreTraining.get_output_embeddings + def get_output_embeddings(self): + return self.cls.predictions.decoder + + # Copied from transformers.models.bert.modeling_bert.BertForPreTraining.set_output_embeddings + def set_output_embeddings(self, new_embeddings): + self.cls.predictions.decoder = new_embeddings + self.cls.predictions.bias = new_embeddings.bias + + @can_return_tuple + @auto_docstring + def forward( + self, + input_ids: torch.Tensor | None = None, + input_shape_ids: torch.Tensor | None = None, + input_pronunciation_ids: torch.Tensor | None = None, + attention_mask: torch.Tensor | None = None, + token_type_ids: torch.Tensor | None = None, + attack_input_ids: torch.Tensor | None = None, + attack_input_shape_ids: torch.Tensor | None = None, + attack_input_pronunciation_ids: torch.Tensor | None = None, + attack_attention_mask: torch.Tensor | None = None, + attack_token_type_ids: torch.Tensor | None = None, + position_ids: torch.Tensor | None = None, + inputs_embeds: torch.Tensor | None = None, + labels_input_ids: torch.Tensor | None = None, + labels_input_shape_ids: torch.Tensor | None = None, + labels_input_pronunciation_ids: torch.Tensor | None = None, + labels_attention_mask: torch.Tensor | None = None, + labels_token_type_ids: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor] | MaskedLMOutput: + r""" + input_shape_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`): + Indices of input sequence tokens in the shape vocabulary. + + Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and + [`PreTrainedTokenizer.__call__`] for details. + + [What are input IDs?](../glossary#input_shape_ids) + input_pronunciation_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`): + Indices of input sequence tokens in the pronunciation vocabulary. + + Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and + [`PreTrainedTokenizer.__call__`] for details. + + [What are input IDs?](../glossary#input_pronunciation_ids) + attack_input_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + attack sample ids for computing the contrastive loss. Indices should be in `[-100, 0, ..., + config.vocab_size]` (see `input_ids` docstring) Tokens with indices set to `-100` are ignored (masked), + the loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]` + attack_input_shape_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + attack sample shape ids for computing the contrastive loss. Indices should be in `[-100, 0, ..., + config.vocab_size]` (see `input_ids` docstring) Tokens with indices set to `-100` are ignored (masked), + the loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]` + attack_input_pronunciation_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + attack sample pronunciation ids for computing the contrastive loss. Indices should be in `[-100, 0, + ..., config.vocab_size]` (see `input_ids` docstring) Tokens with indices set to `-100` are ignored + (masked), the loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]` + attack_attention_mask (`torch.FloatTensor` of shape `(batch_size, sequence_length)`, *optional*): + Mask to avoid performing attention on padding token indices for the attack sample. Mask values selected in + `[0, 1]`: `1` for tokens that are NOT MASKED, `0` for MASKED tokens. + attack_token_type_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Segment token indices to indicate different portions of the attack inputs. Indices are selected in `[0, 1]`: + `0` corresponds to a sentence A token, `1` corresponds to a sentence B token. + labels_input_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + target ids for computing the contrastive loss and masked_lm_loss . Indices should be in `[-100, 0, ..., + config.vocab_size]` (see `input_ids` docstring) Tokens with indices set to `-100` are ignored (masked), + the loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]` + labels_input_shape_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + target shape ids for computing the contrastive loss and masked_lm_loss . Indices should be in `[-100, + 0, ..., config.vocab_size]` (see `input_ids` docstring) Tokens with indices set to `-100` are ignored + (masked), the loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]` + labels_input_pronunciation_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + target pronunciation ids for computing the contrastive loss and masked_lm_loss . Indices should be in + `[-100, 0, ..., config.vocab_size]` (see `input_ids` docstring) Tokens with indices set to `-100` are + ignored (masked), the loss is only computed for the tokens with labels in `[0, ..., + config.vocab_size]` + labels_attention_mask (`torch.FloatTensor` of shape `(batch_size, sequence_length)`, *optional*): + Mask to avoid performing attention on padding token indices for the label sample. Mask values selected in + `[0, 1]`: `1` for tokens that are NOT MASKED, `0` for MASKED tokens. + labels_token_type_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Segment token indices to indicate different portions of the label inputs. Indices are selected in `[0, 1]`: + `0` corresponds to a sentence A token, `1` corresponds to a sentence B token. + + Example: + + ```python + >>> from transformers import AutoTokenizer, RoCBertForPreTraining + >>> import torch + + >>> tokenizer = AutoTokenizer.from_pretrained("weiweishi/roc-bert-base-zh") + >>> model = RoCBertForPreTraining.from_pretrained("weiweishi/roc-bert-base-zh") + + >>> inputs = tokenizer("你好,很高兴认识你", return_tensors="pt") + >>> attack_inputs = {} + >>> for key in list(inputs.keys()): + ... attack_inputs[f"attack_{key}"] = inputs[key] + >>> label_inputs = {} + >>> for key in list(inputs.keys()): + ... label_inputs[f"labels_{key}"] = inputs[key] + + >>> inputs.update(label_inputs) + >>> inputs.update(attack_inputs) + >>> outputs = model(**inputs) + + >>> logits = outputs.logits + >>> logits.shape + torch.Size([1, 11, 21128]) + ``` + """ + outputs = self.roc_bert( + input_ids, + input_shape_ids=input_shape_ids, + input_pronunciation_ids=input_pronunciation_ids, + attention_mask=attention_mask, + token_type_ids=token_type_ids, + position_ids=position_ids, + inputs_embeds=inputs_embeds, + return_dict=True, + **kwargs, + ) + + sequence_output, pooled_output = outputs[:2] + prediction_scores = self.cls(sequence_output) + + loss = None + if labels_input_ids is not None: + loss_fct = CrossEntropyLoss() # -100 index = padding token + masked_lm_loss = loss_fct(prediction_scores.view(-1, self.config.vocab_size), labels_input_ids.view(-1)) + + if attack_input_ids is not None: + batch_size, _ = labels_input_ids.shape + device = labels_input_ids.device + + target_inputs = torch.clone(labels_input_ids) + target_inputs[target_inputs == -100] = self.config.pad_token_id + + labels_output = self.roc_bert( + target_inputs, + input_shape_ids=labels_input_shape_ids, + input_pronunciation_ids=labels_input_pronunciation_ids, + attention_mask=labels_attention_mask, + token_type_ids=labels_token_type_ids, + ) + attack_output = self.roc_bert( + attack_input_ids, + input_shape_ids=attack_input_shape_ids, + input_pronunciation_ids=attack_input_pronunciation_ids, + attention_mask=attack_attention_mask, + token_type_ids=attack_token_type_ids, + ) + + labels_pooled_output = labels_output[1] + attack_pooled_output = attack_output[1] + + pooled_output_norm = torch.nn.functional.normalize(pooled_output, dim=-1) + labels_pooled_output_norm = torch.nn.functional.normalize(labels_pooled_output, dim=-1) + attack_pooled_output_norm = torch.nn.functional.normalize(attack_pooled_output, dim=-1) + + sim_matrix = torch.matmul(pooled_output_norm, attack_pooled_output_norm.T) # batch_size * hidden_dim + sim_matrix_target = torch.matmul(labels_pooled_output_norm, attack_pooled_output_norm.T) + batch_labels = torch.tensor(list(range(batch_size)), device=device) + contrastive_loss = ( + loss_fct(100 * sim_matrix.view(batch_size, -1), batch_labels.view(-1)) + + loss_fct(100 * sim_matrix_target.view(batch_size, -1), batch_labels.view(-1)) + ) / 2 + + loss = contrastive_loss + masked_lm_loss + else: + loss = masked_lm_loss + + return MaskedLMOutput( + loss=loss, + logits=prediction_scores, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + ) + + +@auto_docstring +class RoCBertForMaskedLM(RoCBertPreTrainedModel): + _tied_weights_keys = { + "cls.predictions.decoder.bias": "cls.predictions.bias", + "cls.predictions.decoder.weight": "roc_bert.embeddings.word_embeddings.weight", + } + + # Copied from transformers.models.bert.modeling_bert.BertForMaskedLM.__init__ with Bert->RoCBert,bert->roc_bert + def __init__(self, config): + super().__init__(config) + + if config.is_decoder: + logger.warning( + "If you want to use `RoCBertForMaskedLM` make sure `config.is_decoder=False` for " + "bi-directional self-attention." + ) + + self.roc_bert = RoCBertModel(config, add_pooling_layer=False) + self.cls = RoCBertOnlyMLMHead(config) + + # Initialize weights and apply final processing + self.post_init() + + # Copied from transformers.models.bert.modeling_bert.BertForMaskedLM.get_output_embeddings + def get_output_embeddings(self): + return self.cls.predictions.decoder + + # Copied from transformers.models.bert.modeling_bert.BertForMaskedLM.set_output_embeddings + def set_output_embeddings(self, new_embeddings): + self.cls.predictions.decoder = new_embeddings + self.cls.predictions.bias = new_embeddings.bias + + @can_return_tuple + @auto_docstring + def forward( + self, + input_ids: torch.Tensor | None = None, + input_shape_ids: torch.Tensor | None = None, + input_pronunciation_ids: torch.Tensor | None = None, + attention_mask: torch.Tensor | None = None, + token_type_ids: torch.Tensor | None = None, + position_ids: torch.Tensor | None = None, + inputs_embeds: torch.Tensor | None = None, + encoder_hidden_states: torch.Tensor | None = None, + encoder_attention_mask: torch.Tensor | None = None, + labels: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor] | MaskedLMOutput: + r""" + input_shape_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`): + Indices of input sequence tokens in the shape vocabulary. + + Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and + [`PreTrainedTokenizer.__call__`] for details. + + [What are input IDs?](../glossary#input_shape_ids) + input_pronunciation_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`): + Indices of input sequence tokens in the pronunciation vocabulary. + + Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and + [`PreTrainedTokenizer.__call__`] for details. + + [What are input IDs?](../glossary#input_pronunciation_ids) + labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Labels for computing the masked language modeling loss. Indices should be in `[-100, 0, ..., + config.vocab_size]` (see `input_ids` docstring) Tokens with indices set to `-100` are ignored (masked), the + loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]`. + + Example: + ```python + >>> from transformers import AutoTokenizer, RoCBertForMaskedLM + >>> import torch + + >>> tokenizer = AutoTokenizer.from_pretrained("weiweishi/roc-bert-base-zh") + >>> model = RoCBertForMaskedLM.from_pretrained("weiweishi/roc-bert-base-zh") + + >>> inputs = tokenizer("法国是首都[MASK].", return_tensors="pt") + + >>> with torch.no_grad(): + ... logits = model(**inputs).logits + + >>> # retrieve index of {mask} + >>> mask_token_index = (inputs.input_ids == tokenizer.mask_token_id)[0].nonzero(as_tuple=True)[0] + + >>> predicted_token_id = logits[0, mask_token_index].argmax(axis=-1) + >>> tokenizer.decode(predicted_token_id) + '.' + ``` + """ + outputs = self.roc_bert( + input_ids, + input_shape_ids=input_shape_ids, + input_pronunciation_ids=input_pronunciation_ids, + attention_mask=attention_mask, + token_type_ids=token_type_ids, + position_ids=position_ids, + inputs_embeds=inputs_embeds, + encoder_hidden_states=encoder_hidden_states, + encoder_attention_mask=encoder_attention_mask, + return_dict=True, + **kwargs, + ) + + sequence_output = outputs[0] + prediction_scores = self.cls(sequence_output) + + masked_lm_loss = None + if labels is not None: + loss_fct = CrossEntropyLoss() # -100 index = padding token + masked_lm_loss = loss_fct(prediction_scores.view(-1, self.config.vocab_size), labels.view(-1)) + + return MaskedLMOutput( + loss=masked_lm_loss, + logits=prediction_scores, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + ) + + +@auto_docstring( + custom_intro=""" + RoCBert Model with a `language modeling` head on top for CLM fine-tuning. + """ +) +class RoCBertForCausalLM(RoCBertPreTrainedModel, GenerationMixin): + _tied_weights_keys = { + "cls.predictions.decoder.bias": "cls.predictions.bias", + "cls.predictions.decoder.weight": "roc_bert.embeddings.word_embeddings.weight", + } + + # Copied from transformers.models.bert.modeling_bert.BertLMHeadModel.__init__ with BertLMHeadModel->RoCBertForCausalLM,Bert->RoCBert,bert->roc_bert + def __init__(self, config): + super().__init__(config) + + if not config.is_decoder: + logger.warning("If you want to use `RoCRoCBertForCausalLM` as a standalone, add `is_decoder=True.`") + + self.roc_bert = RoCBertModel(config, add_pooling_layer=False) + self.cls = RoCBertOnlyMLMHead(config) + + # Initialize weights and apply final processing + self.post_init() + + # Copied from transformers.models.bert.modeling_bert.BertLMHeadModel.get_output_embeddings + def get_output_embeddings(self): + return self.cls.predictions.decoder + + # Copied from transformers.models.bert.modeling_bert.BertLMHeadModel.set_output_embeddings + def set_output_embeddings(self, new_embeddings): + self.cls.predictions.decoder = new_embeddings + self.cls.predictions.bias = new_embeddings.bias + + @can_return_tuple + @auto_docstring + def forward( + self, + input_ids: torch.Tensor | None = None, + input_shape_ids: torch.Tensor | None = None, + input_pronunciation_ids: torch.Tensor | None = None, + attention_mask: torch.Tensor | None = None, + token_type_ids: torch.Tensor | None = None, + position_ids: torch.Tensor | None = None, + inputs_embeds: torch.Tensor | None = None, + encoder_hidden_states: torch.Tensor | None = None, + encoder_attention_mask: torch.Tensor | None = None, + past_key_values: list[torch.Tensor] | None = None, + labels: torch.Tensor | None = None, + use_cache: bool | None = None, + cache_position: torch.Tensor | None = None, + logits_to_keep: int | torch.Tensor = 0, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor] | CausalLMOutputWithCrossAttentions: + r""" + input_shape_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`): + Indices of input sequence tokens in the shape vocabulary. + + Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and + [`PreTrainedTokenizer.__call__`] for details. + + [What are input IDs?](../glossary#input_shape_ids) + input_pronunciation_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`): + Indices of input sequence tokens in the pronunciation vocabulary. + + Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and + [`PreTrainedTokenizer.__call__`] for details. + + [What are input IDs?](../glossary#input_pronunciation_ids) + labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Labels for computing the left-to-right language modeling loss (next word prediction). Indices should be in + `[-100, 0, ..., config.vocab_size]` (see `input_ids` docstring) Tokens with indices set to `-100` are + ignored (masked), the loss is only computed for the tokens with labels n `[0, ..., config.vocab_size]`. + + Example: + + ```python + >>> from transformers import AutoTokenizer, RoCBertForCausalLM, RoCBertConfig + >>> import torch + + >>> tokenizer = AutoTokenizer.from_pretrained("weiweishi/roc-bert-base-zh") + >>> config = RoCBertConfig.from_pretrained("weiweishi/roc-bert-base-zh") + >>> config.is_decoder = True + >>> model = RoCBertForCausalLM.from_pretrained("weiweishi/roc-bert-base-zh", config=config) + + >>> inputs = tokenizer("你好,很高兴认识你", return_tensors="pt") + >>> outputs = model(**inputs) + + >>> prediction_logits = outputs.logits + ``` + """ + outputs: BaseModelOutputWithPoolingAndCrossAttentions = self.roc_bert( + input_ids, + input_shape_ids=input_shape_ids, + input_pronunciation_ids=input_pronunciation_ids, + attention_mask=attention_mask, + token_type_ids=token_type_ids, + position_ids=position_ids, + inputs_embeds=inputs_embeds, + encoder_hidden_states=encoder_hidden_states, + encoder_attention_mask=encoder_attention_mask, + past_key_values=past_key_values, + use_cache=use_cache, + cache_position=cache_position, + return_dict=True, + **kwargs, + ) + + hidden_states = outputs.last_hidden_state + # Only compute necessary logits, and do not upcast them to float if we are not computing the loss + slice_indices = slice(-logits_to_keep, None) if isinstance(logits_to_keep, int) else logits_to_keep + logits = self.cls(hidden_states[:, slice_indices, :]) + + loss = None + if labels is not None: + loss = self.loss_function(logits=logits, labels=labels, vocab_size=self.config.vocab_size, **kwargs) + + return CausalLMOutputWithCrossAttentions( + loss=loss, + logits=logits, + past_key_values=outputs.past_key_values, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + cross_attentions=outputs.cross_attentions, + ) + + def prepare_inputs_for_generation( + self, + input_ids, + input_shape_ids=None, + input_pronunciation_ids=None, + past_key_values=None, + attention_mask=None, + **model_kwargs, + ): + # Overwritten -- `input_pronunciation_ids` + + model_inputs = super().prepare_inputs_for_generation( + input_ids=input_ids, + past_key_values=past_key_values, + attention_mask=attention_mask, + **model_kwargs, + ) + + # cut decoder_input_ids if past_key_values is used + if past_key_values is not None: + if input_shape_ids is not None: + model_inputs["input_shape_ids"] = input_shape_ids[:, -1:] + if input_pronunciation_ids is not None: + model_inputs["input_pronunciation_ids"] = input_pronunciation_ids[:, -1:] + + return model_inputs + + +@auto_docstring( + custom_intro=""" + RoCBert Model transformer with a sequence classification/regression head on top (a linear layer on top of + the pooled output) e.g. for GLUE tasks. + """ +) +class RoCBertForSequenceClassification(RoCBertPreTrainedModel): + # Copied from transformers.models.bert.modeling_bert.BertForSequenceClassification.__init__ with Bert->RoCBert,bert->roc_bert + def __init__(self, config): + super().__init__(config) + self.num_labels = config.num_labels + self.config = config + + self.roc_bert = RoCBertModel(config) + classifier_dropout = ( + config.classifier_dropout if config.classifier_dropout is not None else config.hidden_dropout_prob + ) + self.dropout = nn.Dropout(classifier_dropout) + self.classifier = nn.Linear(config.hidden_size, config.num_labels) + + # Initialize weights and apply final processing + self.post_init() + + @can_return_tuple + @auto_docstring + def forward( + self, + input_ids: torch.Tensor | None = None, + input_shape_ids: torch.Tensor | None = None, + input_pronunciation_ids: torch.Tensor | None = None, + attention_mask: torch.Tensor | None = None, + token_type_ids: torch.Tensor | None = None, + position_ids: torch.Tensor | None = None, + inputs_embeds: torch.Tensor | None = None, + labels: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor] | SequenceClassifierOutput: + r""" + input_shape_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`): + Indices of input sequence tokens in the shape vocabulary. + + Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and + [`PreTrainedTokenizer.__call__`] for details. + + [What are input IDs?](../glossary#input_shape_ids) + input_pronunciation_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`): + Indices of input sequence tokens in the pronunciation vocabulary. + + Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and + [`PreTrainedTokenizer.__call__`] for details. + + [What are input IDs?](../glossary#input_pronunciation_ids) + labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*): + Labels for computing the sequence classification/regression loss. Indices should be in `[0, ..., + config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If + `config.num_labels > 1` a classification loss is computed (Cross-Entropy). + """ + outputs = self.roc_bert( + input_ids, + input_shape_ids=input_shape_ids, + input_pronunciation_ids=input_pronunciation_ids, + attention_mask=attention_mask, + token_type_ids=token_type_ids, + position_ids=position_ids, + inputs_embeds=inputs_embeds, + return_dict=True, + **kwargs, + ) + + pooled_output = outputs[1] + + pooled_output = self.dropout(pooled_output) + logits = self.classifier(pooled_output) + + loss = None + if labels is not None: + if self.config.problem_type is None: + if self.num_labels == 1: + self.config.problem_type = "regression" + elif self.num_labels > 1 and (labels.dtype == torch.long or labels.dtype == torch.int): + self.config.problem_type = "single_label_classification" + else: + self.config.problem_type = "multi_label_classification" + + if self.config.problem_type == "regression": + loss_fct = MSELoss() + if self.num_labels == 1: + loss = loss_fct(logits.squeeze(), labels.squeeze()) + else: + loss = loss_fct(logits, labels) + elif self.config.problem_type == "single_label_classification": + loss_fct = CrossEntropyLoss() + loss = loss_fct(logits.view(-1, self.num_labels), labels.view(-1)) + elif self.config.problem_type == "multi_label_classification": + loss_fct = BCEWithLogitsLoss() + loss = loss_fct(logits, labels) + + return SequenceClassifierOutput( + loss=loss, + logits=logits, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + ) + + +@auto_docstring +class RoCBertForMultipleChoice(RoCBertPreTrainedModel): + # Copied from transformers.models.bert.modeling_bert.BertForMultipleChoice.__init__ with Bert->RoCBert,bert->roc_bert + def __init__(self, config): + super().__init__(config) + + self.roc_bert = RoCBertModel(config) + classifier_dropout = ( + config.classifier_dropout if config.classifier_dropout is not None else config.hidden_dropout_prob + ) + self.dropout = nn.Dropout(classifier_dropout) + self.classifier = nn.Linear(config.hidden_size, 1) + + # Initialize weights and apply final processing + self.post_init() + + @can_return_tuple + @auto_docstring + def forward( + self, + input_ids: torch.Tensor | None = None, + input_shape_ids: torch.Tensor | None = None, + input_pronunciation_ids: torch.Tensor | None = None, + attention_mask: torch.Tensor | None = None, + token_type_ids: torch.Tensor | None = None, + position_ids: torch.Tensor | None = None, + inputs_embeds: torch.Tensor | None = None, + labels: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor] | MultipleChoiceModelOutput: + r""" + input_ids (`torch.LongTensor` of shape `(batch_size, num_choices, sequence_length)`): + Indices of input sequence tokens in the vocabulary. + + Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and + [`PreTrainedTokenizer.__call__`] for details. + + [What are input IDs?](../glossary#input-ids) + input_shape_ids (`torch.LongTensor` of shape `(batch_size, num_choices, sequence_length)`): + Indices of input sequence tokens in the shape vocabulary. + + Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and + [`PreTrainedTokenizer.__call__`] for details. + + [What are input IDs?](../glossary#input_shape_ids) + input_pronunciation_ids (`torch.LongTensor` of shape `(batch_size, num_choices, sequence_length)`): + Indices of input sequence tokens in the pronunciation vocabulary. + + Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and + [`PreTrainedTokenizer.__call__`] for details. + + [What are input IDs?](../glossary#input_pronunciation_ids) + token_type_ids (`torch.LongTensor` of shape `(batch_size, num_choices, sequence_length)`, *optional*): + Segment token indices to indicate first and second portions of the inputs. Indices are selected in `[0, + 1]`: + + - 0 corresponds to a *sentence A* token, + - 1 corresponds to a *sentence B* token. + + [What are token type IDs?](../glossary#token-type-ids) + position_ids (`torch.LongTensor` of shape `(batch_size, num_choices, sequence_length)`, *optional*): + Indices of positions of each input sequence tokens in the position embeddings. Selected in the range `[0, + config.max_position_embeddings - 1]`. + + [What are position IDs?](../glossary#position-ids) + inputs_embeds (`torch.FloatTensor` of shape `(batch_size, num_choices, sequence_length, hidden_size)`, *optional*): + Optionally, instead of passing `input_ids` you can choose to directly pass an embedded representation. This + is useful if you want more control over how to convert *input_ids* indices into associated vectors than the + model's internal embedding lookup matrix. + labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*): + Labels for computing the multiple choice classification loss. Indices should be in `[0, ..., + num_choices-1]` where `num_choices` is the size of the second dimension of the input tensors. (See + `input_ids` above) + """ + num_choices = input_ids.shape[1] if input_ids is not None else inputs_embeds.shape[1] + + input_ids = input_ids.view(-1, input_ids.size(-1)) if input_ids is not None else None + input_shape_ids = input_shape_ids.view(-1, input_shape_ids.size(-1)) if input_shape_ids is not None else None + input_pronunciation_ids = ( + input_pronunciation_ids.view(-1, input_pronunciation_ids.size(-1)) + if input_pronunciation_ids is not None + else None + ) + attention_mask = attention_mask.view(-1, attention_mask.size(-1)) if attention_mask is not None else None + token_type_ids = token_type_ids.view(-1, token_type_ids.size(-1)) if token_type_ids is not None else None + position_ids = position_ids.view(-1, position_ids.size(-1)) if position_ids is not None else None + inputs_embeds = ( + inputs_embeds.view(-1, inputs_embeds.size(-2), inputs_embeds.size(-1)) + if inputs_embeds is not None + else None + ) + + outputs = self.roc_bert( + input_ids, + input_shape_ids=input_shape_ids, + input_pronunciation_ids=input_pronunciation_ids, + attention_mask=attention_mask, + token_type_ids=token_type_ids, + position_ids=position_ids, + inputs_embeds=inputs_embeds, + return_dict=True, + **kwargs, + ) + + pooled_output = outputs[1] + + pooled_output = self.dropout(pooled_output) + logits = self.classifier(pooled_output) + reshaped_logits = logits.view(-1, num_choices) + + loss = None + if labels is not None: + loss_fct = CrossEntropyLoss() + loss = loss_fct(reshaped_logits, labels) + + return MultipleChoiceModelOutput( + loss=loss, + logits=reshaped_logits, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + ) + + +@auto_docstring +class RoCBertForTokenClassification(RoCBertPreTrainedModel): + # Copied from transformers.models.bert.modeling_bert.BertForTokenClassification.__init__ with Bert->RoCBert,bert->roc_bert + def __init__(self, config): + super().__init__(config) + self.num_labels = config.num_labels + + self.roc_bert = RoCBertModel(config, add_pooling_layer=False) + classifier_dropout = ( + config.classifier_dropout if config.classifier_dropout is not None else config.hidden_dropout_prob + ) + self.dropout = nn.Dropout(classifier_dropout) + self.classifier = nn.Linear(config.hidden_size, config.num_labels) + + # Initialize weights and apply final processing + self.post_init() + + @can_return_tuple + @auto_docstring + def forward( + self, + input_ids: torch.Tensor | None = None, + input_shape_ids: torch.Tensor | None = None, + input_pronunciation_ids: torch.Tensor | None = None, + attention_mask: torch.Tensor | None = None, + token_type_ids: torch.Tensor | None = None, + position_ids: torch.Tensor | None = None, + inputs_embeds: torch.Tensor | None = None, + labels: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple | TokenClassifierOutput: + r""" + input_shape_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`): + Indices of input sequence tokens in the shape vocabulary. + + Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and + [`PreTrainedTokenizer.__call__`] for details. + + [What are input IDs?](../glossary#input_shape_ids) + input_pronunciation_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`): + Indices of input sequence tokens in the pronunciation vocabulary. + + Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and + [`PreTrainedTokenizer.__call__`] for details. + + [What are input IDs?](../glossary#input_pronunciation_ids) + labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Labels for computing the token classification loss. Indices should be in `[0, ..., config.num_labels - 1]`. + """ + outputs = self.roc_bert( + input_ids, + input_shape_ids=input_shape_ids, + input_pronunciation_ids=input_pronunciation_ids, + attention_mask=attention_mask, + token_type_ids=token_type_ids, + position_ids=position_ids, + inputs_embeds=inputs_embeds, + return_dict=True, + **kwargs, + ) + + sequence_output = outputs[0] + + sequence_output = self.dropout(sequence_output) + logits = self.classifier(sequence_output) + + loss = None + if labels is not None: + loss_fct = CrossEntropyLoss() + loss = loss_fct(logits.view(-1, self.num_labels), labels.view(-1)) + + return TokenClassifierOutput( + loss=loss, + logits=logits, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + ) + + +@auto_docstring +class RoCBertForQuestionAnswering(RoCBertPreTrainedModel): + # Copied from transformers.models.bert.modeling_bert.BertForQuestionAnswering.__init__ with Bert->RoCBert,bert->roc_bert + def __init__(self, config): + super().__init__(config) + self.num_labels = config.num_labels + + self.roc_bert = RoCBertModel(config, add_pooling_layer=False) + self.qa_outputs = nn.Linear(config.hidden_size, config.num_labels) + + # Initialize weights and apply final processing + self.post_init() + + @can_return_tuple + @auto_docstring + def forward( + self, + input_ids: torch.Tensor | None = None, + input_shape_ids: torch.Tensor | None = None, + input_pronunciation_ids: torch.Tensor | None = None, + attention_mask: torch.Tensor | None = None, + token_type_ids: torch.Tensor | None = None, + position_ids: torch.Tensor | None = None, + inputs_embeds: torch.Tensor | None = None, + start_positions: torch.Tensor | None = None, + end_positions: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor] | QuestionAnsweringModelOutput: + r""" + input_shape_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`): + Indices of input sequence tokens in the shape vocabulary. + + Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and + [`PreTrainedTokenizer.__call__`] for details. + + [What are input IDs?](../glossary#input_shape_ids) + input_pronunciation_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`): + Indices of input sequence tokens in the pronunciation vocabulary. + + Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and + [`PreTrainedTokenizer.__call__`] for details. + + [What are input IDs?](../glossary#input_pronunciation_ids) + """ + outputs = self.roc_bert( + input_ids, + input_shape_ids=input_shape_ids, + input_pronunciation_ids=input_pronunciation_ids, + attention_mask=attention_mask, + token_type_ids=token_type_ids, + position_ids=position_ids, + inputs_embeds=inputs_embeds, + return_dict=True, + **kwargs, + ) + + sequence_output = outputs[0] + + logits = self.qa_outputs(sequence_output) + start_logits, end_logits = logits.split(1, dim=-1) + start_logits = start_logits.squeeze(-1) + end_logits = end_logits.squeeze(-1) + + total_loss = None + if start_positions is not None and end_positions is not None: + # If we are on multi-GPU, split add a dimension + if len(start_positions.size()) > 1: + start_positions = start_positions.squeeze(-1) + if len(end_positions.size()) > 1: + end_positions = end_positions.squeeze(-1) + # sometimes the start/end positions are outside our model inputs, we ignore these terms + ignored_index = start_logits.size(1) + start_positions = start_positions.clamp(0, ignored_index) + end_positions = end_positions.clamp(0, ignored_index) + + loss_fct = CrossEntropyLoss(ignore_index=ignored_index) + start_loss = loss_fct(start_logits, start_positions) + end_loss = loss_fct(end_logits, end_positions) + total_loss = (start_loss + end_loss) / 2 + + return QuestionAnsweringModelOutput( + loss=total_loss, + start_logits=start_logits, + end_logits=end_logits, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + ) + + +__all__ = [ + "RoCBertForCausalLM", + "RoCBertForMaskedLM", + "RoCBertForMultipleChoice", + "RoCBertForPreTraining", + "RoCBertForQuestionAnswering", + "RoCBertForSequenceClassification", + "RoCBertForTokenClassification", + "RoCBertLayer", + "RoCBertModel", + "RoCBertPreTrainedModel", +] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/roc_bert/tokenization_roc_bert.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/roc_bert/tokenization_roc_bert.py new file mode 100644 index 0000000000000000000000000000000000000000..3663ee35f21be3b04af3a931a2e32cee8c39bc46 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/roc_bert/tokenization_roc_bert.py @@ -0,0 +1,1319 @@ +# Copyright 2022 WeChatAI and The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""Tokenization classes for RoCBert.""" + +import collections +import itertools +import json +import os +import unicodedata + +from ...tokenization_python import PreTrainedTokenizer, _is_control, _is_punctuation, _is_whitespace +from ...tokenization_utils_base import ( + ENCODE_KWARGS_DOCSTRING, + ENCODE_PLUS_ADDITIONAL_KWARGS_DOCSTRING, + BatchEncoding, + EncodedInput, + EncodedInputPair, + PaddingStrategy, + PreTokenizedInput, + PreTokenizedInputPair, + TensorType, + TextInput, + TextInputPair, + TruncationStrategy, +) +from ...utils import add_end_docstrings, logging + + +logger = logging.get_logger(__name__) + +VOCAB_FILES_NAMES = { + "vocab_file": "vocab.txt", + "word_shape_file": "word_shape.json", + "word_pronunciation_file": "word_pronunciation.json", +} + + +def load_vocab(vocab_file): + """Loads a vocabulary file into a dictionary.""" + vocab = collections.OrderedDict() + with open(vocab_file, "r", encoding="utf-8") as reader: + tokens = reader.readlines() + for index, token in enumerate(tokens): + token = token.rstrip("\n") + vocab[token] = index + return vocab + + +def whitespace_tokenize(text): + """Runs basic whitespace cleaning and splitting on a piece of text.""" + text = text.strip() + if not text: + return [] + tokens = text.split() + return tokens + + +class RoCBertTokenizer(PreTrainedTokenizer): + r""" + Args: + Construct a RoCBert tokenizer. Based on WordPiece. This tokenizer inherits from [`PreTrainedTokenizer`] which + contains most of the main methods. Users should refer to this superclass for more information regarding those + methods. + vocab_file (`str`): + File containing the vocabulary. + word_shape_file (`str`): + File containing the word => shape info. + word_pronunciation_file (`str`): + File containing the word => pronunciation info. + do_lower_case (`bool`, *optional*, defaults to `True`): + Whether or not to lowercase the input when tokenizing. + do_basic_tokenize (`bool`, *optional*, defaults to `True`): + Whether or not to do basic tokenization before WordPiece. + never_split (`Iterable`, *optional*): + Collection of tokens which will never be split during tokenization. Only has an effect when + `do_basic_tokenize=True` + unk_token (`str`, *optional*, defaults to `"[UNK]"`): + The unknown token. A token that is not in the vocabulary cannot be converted to an ID and is set to be this + token instead. + sep_token (`str`, *optional*, defaults to `"[SEP]"`): + The separator token, which is used when building a sequence from multiple sequences, e.g. two sequences for + sequence classification or for a text and a question for question answering. It is also used as the last + token of a sequence built with special tokens. + pad_token (`str`, *optional*, defaults to `"[PAD]"`): + The token used for padding, for example when batching sequences of different lengths. + cls_token (`str`, *optional*, defaults to `"[CLS]"`): + The classifier token which is used when doing sequence classification (classification of the whole sequence + instead of per-token classification). It is the first token of the sequence when built with special tokens. + mask_token (`str`, *optional*, defaults to `"[MASK]"`): + The token used for masking values. This is the token used when training this model with masked language + modeling. This is the token which the model will try to predict. + tokenize_chinese_chars (`bool`, *optional*, defaults to `True`): + Whether or not to tokenize Chinese characters. This should likely be deactivated for Japanese (see this + [issue](https://github.com/huggingface/transformers/issues/328)). + strip_accents (`bool`, *optional*): + Whether or not to strip all accents. If this option is not specified, then it will be determined by the + value for `lowercase` (as in the original BERT). + """ + + vocab_files_names = VOCAB_FILES_NAMES + + def __init__( + self, + vocab_file, + word_shape_file, + word_pronunciation_file, + do_lower_case=True, + do_basic_tokenize=True, + never_split=None, + unk_token="[UNK]", + sep_token="[SEP]", + pad_token="[PAD]", + cls_token="[CLS]", + mask_token="[MASK]", + tokenize_chinese_chars=True, + strip_accents=None, + **kwargs, + ): + for cur_file in [vocab_file, word_shape_file, word_pronunciation_file]: + if cur_file is None or not os.path.isfile(cur_file): + raise ValueError( + f"Can't find a vocabulary file at path '{vocab_file}'. To load the vocabulary from a Google " + "pretrained model use `tokenizer = RoCBertTokenizer.from_pretrained(PRETRAINED_MODEL_NAME)`" + ) + + self.vocab = load_vocab(vocab_file) + + with open(word_shape_file, "r", encoding="utf8") as in_file: + self.word_shape = json.load(in_file) + + with open(word_pronunciation_file, "r", encoding="utf8") as in_file: + self.word_pronunciation = json.load(in_file) + + self.ids_to_tokens = collections.OrderedDict([(ids, tok) for tok, ids in self.vocab.items()]) + + self.do_basic_tokenize = do_basic_tokenize + if do_basic_tokenize: + self.basic_tokenizer = RoCBertBasicTokenizer( + do_lower_case=do_lower_case, + never_split=never_split, + tokenize_chinese_chars=tokenize_chinese_chars, + strip_accents=strip_accents, + ) + self.wordpiece_tokenizer = RoCBertWordpieceTokenizer(vocab=self.vocab, unk_token=str(unk_token)) + super().__init__( + do_lower_case=do_lower_case, + do_basic_tokenize=do_basic_tokenize, + never_split=never_split, + unk_token=unk_token, + sep_token=sep_token, + pad_token=pad_token, + cls_token=cls_token, + mask_token=mask_token, + tokenize_chinese_chars=tokenize_chinese_chars, + strip_accents=strip_accents, + **kwargs, + ) + + @add_end_docstrings(ENCODE_KWARGS_DOCSTRING, ENCODE_PLUS_ADDITIONAL_KWARGS_DOCSTRING) + def __call__( + self, + text: TextInput | list[TextInput], + text_pair: TextInput | list[TextInput] | None = None, + text_target: TextInput | list[TextInput] | None = None, + add_special_tokens: bool = True, + padding: bool | str | PaddingStrategy = False, + truncation: bool | str | TruncationStrategy = None, + max_length: int | None = None, + max_target_length: int | None = None, + stride: int = 0, + is_split_into_words: bool = False, + pad_to_multiple_of: int | None = None, + padding_side: str | None = None, + return_tensors: str | TensorType | None = None, + return_token_type_ids: bool | None = None, + return_attention_mask: bool | None = None, + return_overflowing_tokens: bool = False, + return_special_tokens_mask: bool = False, + return_offsets_mapping: bool = False, + return_length: bool = False, + verbose: bool = True, + **kwargs, + ) -> BatchEncoding: + # Handle text_target for seq2seq tasks + if text_target is not None: + # Tokenize source text + encodings = self.__call__( + text=text, + text_pair=text_pair, + add_special_tokens=add_special_tokens, + padding=padding, + truncation=truncation, + max_length=max_length, + stride=stride, + is_split_into_words=is_split_into_words, + pad_to_multiple_of=pad_to_multiple_of, + padding_side=padding_side, + return_tensors=return_tensors, + return_token_type_ids=return_token_type_ids, + return_attention_mask=return_attention_mask, + return_overflowing_tokens=return_overflowing_tokens, + return_special_tokens_mask=return_special_tokens_mask, + return_offsets_mapping=return_offsets_mapping, + return_length=return_length, + verbose=verbose, + **kwargs, + ) + # Tokenize target text + target_length = max_target_length if max_target_length is not None else max_length + target_encodings = self.__call__( + text=text_target, + add_special_tokens=add_special_tokens, + padding=padding, + truncation=truncation if target_length is not None else False, + max_length=target_length, + stride=0, + is_split_into_words=is_split_into_words, + pad_to_multiple_of=pad_to_multiple_of, + padding_side=padding_side, + return_tensors=return_tensors, + return_token_type_ids=False, + return_attention_mask=return_attention_mask, + return_overflowing_tokens=False, + return_special_tokens_mask=False, + return_offsets_mapping=False, + return_length=False, + verbose=verbose, + **kwargs, + ) + # Add labels from target input_ids + encodings["labels"] = target_encodings["input_ids"] + return encodings + + # Detect batch vs single + is_batched = isinstance(text, (list, tuple)) and ( + not is_split_into_words or (len(text) > 0 and isinstance(text[0], (list, tuple))) + ) + + if is_batched: + # Build batch tuples of (text, text_pair) if provided + batch_text_or_text_pairs = list(zip(text, text_pair)) if text_pair is not None else text + return self.batch_encode_plus( + batch_text_or_text_pairs=batch_text_or_text_pairs, # type: ignore[arg-type] + add_special_tokens=add_special_tokens, + padding=padding, + truncation=truncation, + max_length=max_length, + stride=stride, + is_split_into_words=is_split_into_words, + pad_to_multiple_of=pad_to_multiple_of, + padding_side=padding_side, + return_tensors=return_tensors, + return_token_type_ids=return_token_type_ids, + return_attention_mask=return_attention_mask, + return_overflowing_tokens=return_overflowing_tokens, + return_special_tokens_mask=return_special_tokens_mask, + return_offsets_mapping=return_offsets_mapping, + return_length=return_length, + verbose=verbose, + **kwargs, + ) + else: + return self.encode_plus( + text=text, + text_pair=text_pair, + add_special_tokens=add_special_tokens, + padding=padding, + truncation=truncation, + max_length=max_length, + stride=stride, + is_split_into_words=is_split_into_words, + pad_to_multiple_of=pad_to_multiple_of, + padding_side=padding_side, + return_tensors=return_tensors, + return_token_type_ids=return_token_type_ids, + return_attention_mask=return_attention_mask, + return_overflowing_tokens=return_overflowing_tokens, + return_special_tokens_mask=return_special_tokens_mask, + return_offsets_mapping=return_offsets_mapping, + return_length=return_length, + verbose=verbose, + **kwargs, + ) + + def encode_plus( + self, + text: TextInput | PreTokenizedInput | EncodedInput, + text_pair: TextInput | PreTokenizedInput | EncodedInput | None = None, + add_special_tokens: bool = True, + padding: bool | str | PaddingStrategy = False, + truncation: bool | str | TruncationStrategy = None, + max_length: int | None = None, + stride: int = 0, + is_split_into_words: bool = False, + pad_to_multiple_of: int | None = None, + padding_side: str | None = None, + return_tensors: str | TensorType | None = None, + return_token_type_ids: bool | None = None, + return_attention_mask: bool | None = None, + return_overflowing_tokens: bool = False, + return_special_tokens_mask: bool = False, + return_offsets_mapping: bool = False, + return_length: bool = False, + verbose: bool = True, + **kwargs, + ) -> BatchEncoding: + padding_strategy, truncation_strategy, max_length, kwargs = self._get_padding_truncation_strategies( + padding=padding, + truncation=truncation, + max_length=max_length, + pad_to_multiple_of=pad_to_multiple_of, + verbose=verbose, + **kwargs, + ) + + return self._encode_plus( + text=text, + text_pair=text_pair, + add_special_tokens=add_special_tokens, + padding_strategy=padding_strategy, + truncation_strategy=truncation_strategy, + max_length=max_length, + stride=stride, + is_split_into_words=is_split_into_words, + pad_to_multiple_of=pad_to_multiple_of, + padding_side=padding_side, + return_tensors=return_tensors, + return_token_type_ids=return_token_type_ids, + return_attention_mask=return_attention_mask, + return_overflowing_tokens=return_overflowing_tokens, + return_special_tokens_mask=return_special_tokens_mask, + return_offsets_mapping=return_offsets_mapping, + return_length=return_length, + verbose=verbose, + **kwargs, + ) + + def batch_encode_plus( + self, + batch_text_or_text_pairs: list[TextInput] + | list[TextInputPair] + | list[PreTokenizedInput] + | list[PreTokenizedInputPair] + | list[EncodedInput] + | list[EncodedInputPair], + add_special_tokens: bool = True, + padding: bool | str | PaddingStrategy = False, + truncation: bool | str | TruncationStrategy = None, + max_length: int | None = None, + stride: int = 0, + is_split_into_words: bool = False, + pad_to_multiple_of: int | None = None, + padding_side: str | None = None, + return_tensors: str | TensorType | None = None, + return_token_type_ids: bool | None = None, + return_attention_mask: bool | None = None, + return_overflowing_tokens: bool = False, + return_special_tokens_mask: bool = False, + return_offsets_mapping: bool = False, + return_length: bool = False, + verbose: bool = True, + **kwargs, + ) -> BatchEncoding: + padding_strategy, truncation_strategy, max_length, kwargs = self._get_padding_truncation_strategies( + padding=padding, + truncation=truncation, + max_length=max_length, + pad_to_multiple_of=pad_to_multiple_of, + verbose=verbose, + **kwargs, + ) + + return self._batch_encode_plus( + batch_text_or_text_pairs=batch_text_or_text_pairs, + add_special_tokens=add_special_tokens, + padding_strategy=padding_strategy, + truncation_strategy=truncation_strategy, + max_length=max_length, + stride=stride, + is_split_into_words=is_split_into_words, + pad_to_multiple_of=pad_to_multiple_of, + padding_side=padding_side, + return_tensors=return_tensors, + return_token_type_ids=return_token_type_ids, + return_attention_mask=return_attention_mask, + return_overflowing_tokens=return_overflowing_tokens, + return_special_tokens_mask=return_special_tokens_mask, + return_offsets_mapping=return_offsets_mapping, + return_length=return_length, + verbose=verbose, + **kwargs, + ) + + @property + def do_lower_case(self): + return self.basic_tokenizer.do_lower_case + + @property + def vocab_size(self): + return len(self.vocab) + + def get_vocab(self): + return dict(self.vocab, **self.added_tokens_encoder) + + def _tokenize(self, text, split_special_tokens=False): + split_tokens = [] + if self.do_basic_tokenize: + for token in self.basic_tokenizer.tokenize( + text, never_split=self.all_special_tokens if not split_special_tokens else None + ): + # If the token is part of the never_split set + if token in self.basic_tokenizer.never_split: + split_tokens.append(token) + else: + split_tokens += self.wordpiece_tokenizer.tokenize(token) + else: + split_tokens = self.wordpiece_tokenizer.tokenize(text) + return split_tokens + + def _encode_plus( + self, + text: TextInput | PreTokenizedInput | EncodedInput, + text_pair: TextInput | PreTokenizedInput | EncodedInput | None = None, + add_special_tokens: bool = True, + padding_strategy: PaddingStrategy = PaddingStrategy.DO_NOT_PAD, + truncation_strategy: TruncationStrategy = TruncationStrategy.DO_NOT_TRUNCATE, + max_length: int | None = None, + stride: int = 0, + is_split_into_words: bool = False, + pad_to_multiple_of: int | None = None, + padding_side: str | None = None, + return_tensors: str | TensorType | None = None, + return_token_type_ids: bool | None = None, + return_attention_mask: bool | None = None, + return_overflowing_tokens: bool = False, + return_special_tokens_mask: bool = False, + return_offsets_mapping: bool = False, + return_length: bool = False, + verbose: bool = True, + **kwargs, + ) -> BatchEncoding: + def get_input_ids(text): + if isinstance(text, str): + tokens = self.tokenize(text, **kwargs) + tokens_ids = self.convert_tokens_to_ids(tokens) + tokens_shape_ids = self.convert_tokens_to_shape_ids(tokens) + tokens_proun_ids = self.convert_tokens_to_pronunciation_ids(tokens) + return tokens_ids, tokens_shape_ids, tokens_proun_ids + elif isinstance(text, (list, tuple)) and len(text) > 0 and isinstance(text[0], str): + if is_split_into_words: + tokens = list( + itertools.chain(*(self.tokenize(t, is_split_into_words=True, **kwargs) for t in text)) + ) + tokens_ids = self.convert_tokens_to_ids(tokens) + tokens_shape_ids = self.convert_tokens_to_shape_ids(tokens) + tokens_proun_ids = self.convert_tokens_to_pronunciation_ids(tokens) + return tokens_ids, tokens_shape_ids, tokens_proun_ids + else: + tokens_ids = self.convert_tokens_to_ids(text) + tokens_shape_ids = self.convert_tokens_to_shape_ids(text) + tokens_proun_ids = self.convert_tokens_to_pronunciation_ids(text) + return tokens_ids, tokens_shape_ids, tokens_proun_ids + elif isinstance(text, (list, tuple)) and len(text) > 0 and isinstance(text[0], int): + return text, [0] * len(text), [0] * len(text) # shape and proun id is pad_value + else: + if is_split_into_words: + raise ValueError( + f"Input {text} is not valid. Should be a string or a list/tuple of strings when" + " `is_split_into_words=True`." + ) + else: + raise ValueError( + f"Input {text} is not valid. Should be a string, a list/tuple of strings or a list/tuple of" + " integers." + ) + + if return_offsets_mapping: + raise NotImplementedError( + "return_offset_mapping is not available when using Python tokenizers. " + "To use this feature, change your tokenizer to one deriving from " + "transformers.PreTrainedTokenizerFast. " + "More information on available tokenizers at " + "https://github.com/huggingface/transformers/pull/2674" + ) + + first_ids, first_shape_ids, first_proun_ids = get_input_ids(text) + if text_pair is not None: + second_ids, second_shape_ids, second_proun_ids = get_input_ids(text_pair) + else: + second_ids, second_shape_ids, second_proun_ids = None, None, None + + return self.prepare_for_model( + first_ids, + first_shape_ids, + first_proun_ids, + pair_ids=second_ids, + pair_shape_ids=second_shape_ids, + pair_pronunciation_ids=second_proun_ids, + add_special_tokens=add_special_tokens, + padding=padding_strategy.value, + truncation=truncation_strategy.value, + max_length=max_length, + stride=stride, + pad_to_multiple_of=pad_to_multiple_of, + padding_side=padding_side, + return_tensors=return_tensors, + prepend_batch_axis=True, + return_attention_mask=return_attention_mask, + return_token_type_ids=return_token_type_ids, + return_overflowing_tokens=return_overflowing_tokens, + return_special_tokens_mask=return_special_tokens_mask, + return_length=return_length, + verbose=verbose, + ) + + @add_end_docstrings(ENCODE_KWARGS_DOCSTRING, ENCODE_PLUS_ADDITIONAL_KWARGS_DOCSTRING) + def prepare_for_model( + self, + ids: list[int], + shape_ids: list[int], + pronunciation_ids: list[int], + pair_ids: list[int] | None = None, + pair_shape_ids: list[int] | None = None, + pair_pronunciation_ids: list[int] | None = None, + add_special_tokens: bool = True, + padding: bool | str | PaddingStrategy = False, + truncation: bool | str | TruncationStrategy = None, + max_length: int | None = None, + stride: int = 0, + pad_to_multiple_of: int | None = None, + padding_side: str | None = None, + return_tensors: str | TensorType | None = None, + return_token_type_ids: bool | None = None, + return_attention_mask: bool | None = None, + return_overflowing_tokens: bool = False, + return_special_tokens_mask: bool = False, + return_offsets_mapping: bool = False, + return_length: bool = False, + verbose: bool = True, + prepend_batch_axis: bool = False, + **kwargs, + ) -> BatchEncoding: + """ + Prepares a sequence of input id, or a pair of sequences of inputs ids so that it can be used by the model. It + adds special tokens, truncates sequences if overflowing while taking into account the special tokens and + manages a moving window (with user defined stride) for overflowing tokens. Please Note, for *pair_ids* + different than `None` and *truncation_strategy = longest_first* or `True`, it is not possible to return + overflowing tokens. Such a combination of arguments will raise an error. + + Args: + ids (`List[int]`): + Tokenized input ids of the first sequence. Can be obtained from a string by chaining the `tokenize` and + `convert_tokens_to_id` methods. + shape_ids (`List[int]`): + Tokenized input ids of the first sequence. Can be obtained from a string by chaining the `tokenize` and + `convert_token_to_shape_id` methods. + pronunciation_ids (`List[int]`): + Tokenized input ids of the first sequence. Can be obtained from a string by chaining the `tokenize` and + `convert_token_to_pronunciation_id` methods. + pair_ids (`List[int]`, *optional*): + Tokenized input ids of the second sequence. Can be obtained from a string by chaining the `tokenize` + and `convert_tokens_to_id` methods. + pair_shape_ids (`List[int]`, *optional*): + Tokenized input ids of the second sequence. Can be obtained from a string by chaining the `tokenize` + and `convert_token_to_shape_id` methods. + pair_pronunciation_ids (`List[int]`, *optional*): + Tokenized input ids of the second sequence. Can be obtained from a string by chaining the `tokenize` + and `convert_token_to_pronunciation_id` methods. + """ + + # Backward compatibility for 'truncation_strategy', 'pad_to_max_length' + padding_strategy, truncation_strategy, max_length, kwargs = self._get_padding_truncation_strategies( + padding=padding, + truncation=truncation, + max_length=max_length, + pad_to_multiple_of=pad_to_multiple_of, + verbose=verbose, + **kwargs, + ) + + pair = bool(pair_ids is not None) + len_ids = len(ids) + len_pair_ids = len(pair_ids) if pair else 0 + + if return_token_type_ids and not add_special_tokens: + raise ValueError( + "Asking to return token_type_ids while setting add_special_tokens to False " + "results in an undefined behavior. Please set add_special_tokens to True or " + "set return_token_type_ids to None." + ) + + if ( + return_overflowing_tokens + and truncation_strategy == TruncationStrategy.LONGEST_FIRST + and pair_ids is not None + ): + raise ValueError( + "Not possible to return overflowing tokens for pair of sequences with the " + "`longest_first`. Please select another truncation strategy than `longest_first`, " + "for instance `only_second` or `only_first`." + ) + + # Load from model defaults + if return_token_type_ids is None: + return_token_type_ids = "token_type_ids" in self.model_input_names + if return_attention_mask is None: + return_attention_mask = "attention_mask" in self.model_input_names + + encoded_inputs = {} + + # Compute the total size of the returned encodings + total_len = len_ids + len_pair_ids + (self.num_special_tokens_to_add(pair=pair) if add_special_tokens else 0) + + # Truncation: Handle max sequence length + overflowing_tokens = [] + if truncation_strategy != TruncationStrategy.DO_NOT_TRUNCATE and max_length and total_len > max_length: + ids, pair_ids, overflowing_tokens = self.truncate_sequences( + ids, + pair_ids=pair_ids, + num_tokens_to_remove=total_len - max_length, + truncation_strategy=truncation_strategy, + stride=stride, + ) + shape_ids, pair_shape_ids, _ = self.truncate_sequences( + shape_ids, + pair_ids=pair_shape_ids, + num_tokens_to_remove=total_len - max_length, + truncation_strategy=truncation_strategy, + stride=stride, + ) + pronunciation_ids, pair_pronunciation_ids, _ = self.truncate_sequences( + pronunciation_ids, + pair_ids=pair_pronunciation_ids, + num_tokens_to_remove=total_len - max_length, + truncation_strategy=truncation_strategy, + stride=stride, + ) + + if return_overflowing_tokens and not return_tensors and overflowing_tokens: + encoded_inputs["overflowing_tokens"] = overflowing_tokens + encoded_inputs["num_truncated_tokens"] = total_len - max_length if max_length else 0 + + # Add special tokens + if add_special_tokens: + sequence = self.build_inputs_with_special_tokens(ids, pair_ids) + token_type_ids = self.create_token_type_ids_from_sequences(ids, pair_ids) + input_shape_ids = self.build_inputs_with_special_tokens( + shape_ids, pair_shape_ids, self.word_shape["[UNK]"], self.word_shape["[UNK]"] + ) + input_pronunciation_ids = self.build_inputs_with_special_tokens( + pronunciation_ids, + pair_pronunciation_ids, + self.word_pronunciation["[UNK]"], + self.word_pronunciation["[UNK]"], + ) + else: + sequence = ids + pair_ids if pair_ids else ids + token_type_ids = [0] * len(ids) + ([0] * len(pair_ids) if pair_ids else []) + input_shape_ids = shape_ids + pair_shape_ids if pair_shape_ids else shape_ids + input_pronunciation_ids = ( + pronunciation_ids + pair_pronunciation_ids if pair_pronunciation_ids else pronunciation_ids + ) + + # Build output dictionary + encoded_inputs["input_ids"] = sequence + encoded_inputs["input_shape_ids"] = input_shape_ids + encoded_inputs["input_pronunciation_ids"] = input_pronunciation_ids + if return_token_type_ids: + encoded_inputs["token_type_ids"] = token_type_ids + if return_special_tokens_mask: + if add_special_tokens: + encoded_inputs["special_tokens_mask"] = self.get_special_tokens_mask(ids, pair_ids) + else: + encoded_inputs["special_tokens_mask"] = [0] * len(sequence) + + # Check lengths + self._eventual_warn_about_too_long_sequence(encoded_inputs["input_ids"], max_length, verbose) + + # Padding + if padding_strategy != PaddingStrategy.DO_NOT_PAD or return_attention_mask: + encoded_inputs = self.pad( + encoded_inputs, + max_length=max_length, + padding=padding_strategy.value, + pad_to_multiple_of=pad_to_multiple_of, + padding_side=padding_side, + return_attention_mask=return_attention_mask, + ) + + if return_length: + encoded_inputs["length"] = len(encoded_inputs["input_ids"]) + + batch_outputs = BatchEncoding( + encoded_inputs, tensor_type=return_tensors, prepend_batch_axis=prepend_batch_axis + ) + + return batch_outputs + + def _pad( + self, + encoded_inputs: dict[str, EncodedInput] | BatchEncoding, + max_length: int | None = None, + padding_strategy: PaddingStrategy = PaddingStrategy.DO_NOT_PAD, + pad_to_multiple_of: int | None = None, + padding_side: str | None = None, + return_attention_mask: bool | None = None, + ) -> dict: + # Load from model defaults + if return_attention_mask is None: + return_attention_mask = "attention_mask" in self.model_input_names + + required_input = encoded_inputs[self.model_input_names[0]] + + if padding_strategy == PaddingStrategy.LONGEST: + max_length = len(required_input) + + if max_length is not None and pad_to_multiple_of is not None and (max_length % pad_to_multiple_of != 0): + max_length = ((max_length // pad_to_multiple_of) + 1) * pad_to_multiple_of + + needs_to_be_padded = padding_strategy != PaddingStrategy.DO_NOT_PAD and len(required_input) != max_length + + # Initialize attention mask if not present. + if return_attention_mask and "attention_mask" not in encoded_inputs: + encoded_inputs["attention_mask"] = [1] * len(required_input) + + if needs_to_be_padded: + difference = max_length - len(required_input) + padding_side = padding_side if padding_side is not None else self.padding_side + + if padding_side == "right": + if return_attention_mask: + encoded_inputs["attention_mask"] = encoded_inputs["attention_mask"] + [0] * difference + if "token_type_ids" in encoded_inputs: + encoded_inputs["token_type_ids"] = ( + encoded_inputs["token_type_ids"] + [self.pad_token_type_id] * difference + ) + if "special_tokens_mask" in encoded_inputs: + encoded_inputs["special_tokens_mask"] = encoded_inputs["special_tokens_mask"] + [1] * difference + for key in ["input_shape_ids", "input_pronunciation_ids"]: + if key in encoded_inputs: + encoded_inputs[key] = encoded_inputs[key] + [self.pad_token_id] * difference + encoded_inputs[self.model_input_names[0]] = required_input + [self.pad_token_id] * difference + elif padding_side == "left": + if return_attention_mask: + encoded_inputs["attention_mask"] = [0] * difference + encoded_inputs["attention_mask"] + if "token_type_ids" in encoded_inputs: + encoded_inputs["token_type_ids"] = [self.pad_token_type_id] * difference + encoded_inputs[ + "token_type_ids" + ] + if "special_tokens_mask" in encoded_inputs: + encoded_inputs["special_tokens_mask"] = [1] * difference + encoded_inputs["special_tokens_mask"] + for key in ["input_shape_ids", "input_pronunciation_ids"]: + if key in encoded_inputs: + encoded_inputs[key] = [self.pad_token_id] * difference + encoded_inputs[key] + encoded_inputs[self.model_input_names[0]] = [self.pad_token_id] * difference + required_input + else: + raise ValueError("Invalid padding strategy:" + str(padding_side)) + + return encoded_inputs + + def _batch_encode_plus( + self, + batch_text_or_text_pairs: list[TextInput] + | list[TextInputPair] + | list[PreTokenizedInput] + | list[PreTokenizedInputPair] + | list[EncodedInput] + | list[EncodedInputPair], + add_special_tokens: bool = True, + padding_strategy: PaddingStrategy = PaddingStrategy.DO_NOT_PAD, + truncation_strategy: TruncationStrategy = TruncationStrategy.DO_NOT_TRUNCATE, + max_length: int | None = None, + stride: int = 0, + is_split_into_words: bool = False, + pad_to_multiple_of: int | None = None, + padding_side: str | None = None, + return_tensors: str | TensorType | None = None, + return_token_type_ids: bool | None = None, + return_attention_mask: bool | None = None, + return_overflowing_tokens: bool = False, + return_special_tokens_mask: bool = False, + return_offsets_mapping: bool = False, + return_length: bool = False, + verbose: bool = True, + **kwargs, + ) -> BatchEncoding: + def get_input_ids(text): + if isinstance(text, str): + tokens = self.tokenize(text, **kwargs) + tokens_ids = self.convert_tokens_to_ids(tokens) + tokens_shape_ids = self.convert_tokens_to_shape_ids(tokens) + tokens_proun_ids = self.convert_tokens_to_pronunciation_ids(tokens) + return tokens_ids, tokens_shape_ids, tokens_proun_ids + elif isinstance(text, (list, tuple)) and len(text) > 0 and isinstance(text[0], str): + if is_split_into_words: + tokens = list( + itertools.chain(*(self.tokenize(t, is_split_into_words=True, **kwargs) for t in text)) + ) + tokens_ids = self.convert_tokens_to_ids(tokens) + tokens_shape_ids = self.convert_tokens_to_shape_ids(tokens) + tokens_proun_ids = self.convert_tokens_to_pronunciation_ids(tokens) + return tokens_ids, tokens_shape_ids, tokens_proun_ids + else: + tokens_ids = self.convert_tokens_to_ids(text) + tokens_shape_ids = self.convert_tokens_to_shape_ids(text) + tokens_proun_ids = self.convert_tokens_to_pronunciation_ids(text) + return tokens_ids, tokens_shape_ids, tokens_proun_ids + elif isinstance(text, (list, tuple)) and len(text) > 0 and isinstance(text[0], int): + return text, [0] * len(text), [0] * len(text) # shape and proun id is pad_value + else: + raise ValueError( + "Input is not valid. Should be a string, a list/tuple of strings or a list/tuple of integers." + ) + + if return_offsets_mapping: + raise NotImplementedError( + "return_offset_mapping is not available when using Python tokenizers. " + "To use this feature, change your tokenizer to one deriving from " + "transformers.PreTrainedTokenizerFast." + ) + + input_ids = [] + input_shape_ids = [] + input_pronunciation_ids = [] + for ids_or_pair_ids in batch_text_or_text_pairs: + if not isinstance(ids_or_pair_ids, (list, tuple)): + ids, pair_ids = ids_or_pair_ids, None + elif is_split_into_words and not isinstance(ids_or_pair_ids[0], (list, tuple)): + ids, pair_ids = ids_or_pair_ids, None + else: + ids, pair_ids = ids_or_pair_ids + + first_ids, first_shape_ids, first_proun_ids = get_input_ids(ids) + if pair_ids is not None: + second_ids, second_shape_ids, second_proun_ids = get_input_ids(pair_ids) + else: + second_ids, second_shape_ids, second_proun_ids = None, None, None + + input_ids.append((first_ids, second_ids)) + input_shape_ids.append((first_shape_ids, second_shape_ids)) + input_pronunciation_ids.append((first_proun_ids, second_proun_ids)) + + batch_outputs = self._batch_prepare_for_model( + input_ids, + batch_shape_ids_pairs=input_shape_ids, + batch_pronunciation_ids_pairs=input_pronunciation_ids, + add_special_tokens=add_special_tokens, + padding_strategy=padding_strategy, + truncation_strategy=truncation_strategy, + max_length=max_length, + stride=stride, + pad_to_multiple_of=pad_to_multiple_of, + padding_side=padding_side, + return_attention_mask=return_attention_mask, + return_token_type_ids=return_token_type_ids, + return_overflowing_tokens=return_overflowing_tokens, + return_special_tokens_mask=return_special_tokens_mask, + return_length=return_length, + return_tensors=return_tensors, + verbose=verbose, + ) + + return batch_outputs + + @add_end_docstrings(ENCODE_KWARGS_DOCSTRING, ENCODE_PLUS_ADDITIONAL_KWARGS_DOCSTRING) + def _batch_prepare_for_model( + self, + batch_ids_pairs: list[PreTokenizedInputPair | tuple[list[int], None]], + batch_shape_ids_pairs: list[PreTokenizedInputPair | tuple[list[int], None]], + batch_pronunciation_ids_pairs: list[PreTokenizedInputPair | tuple[list[int], None]], + add_special_tokens: bool = True, + padding_strategy: PaddingStrategy = PaddingStrategy.DO_NOT_PAD, + truncation_strategy: TruncationStrategy = TruncationStrategy.DO_NOT_TRUNCATE, + max_length: int | None = None, + stride: int = 0, + pad_to_multiple_of: int | None = None, + padding_side: str | None = None, + return_tensors: str | None = None, + return_token_type_ids: bool | None = None, + return_attention_mask: bool | None = None, + return_overflowing_tokens: bool = False, + return_special_tokens_mask: bool = False, + return_length: bool = False, + verbose: bool = True, + ) -> BatchEncoding: + """ + Prepares a sequence of input id, or a pair of sequences of inputs ids so that it can be used by the model. It + adds special tokens, truncates sequences if overflowing while taking into account the special tokens and + manages a moving window (with user defined stride) for overflowing tokens + + Args: + batch_ids_pairs: list of tokenized input ids or input ids pairs + batch_shape_ids_pairs: list of tokenized input shape ids or input shape ids pairs + batch_pronunciation_ids_pairs: list of tokenized input pronunciation ids or input pronunciation ids pairs + """ + + batch_outputs = {} + for i, (first_ids, second_ids) in enumerate(batch_ids_pairs): + first_shape_ids, second_shape_ids = batch_shape_ids_pairs[i] + first_pronunciation_ids, second_pronunciation_ids = batch_pronunciation_ids_pairs[i] + outputs = self.prepare_for_model( + first_ids, + first_shape_ids, + first_pronunciation_ids, + pair_ids=second_ids, + pair_shape_ids=second_shape_ids, + pair_pronunciation_ids=second_pronunciation_ids, + add_special_tokens=add_special_tokens, + padding=PaddingStrategy.DO_NOT_PAD.value, # we pad in batch afterward + truncation=truncation_strategy.value, + max_length=max_length, + stride=stride, + pad_to_multiple_of=None, # we pad in batch afterward + padding_side=None, # we pad in batch afterward + return_attention_mask=False, # we pad in batch afterward + return_token_type_ids=return_token_type_ids, + return_overflowing_tokens=return_overflowing_tokens, + return_special_tokens_mask=return_special_tokens_mask, + return_length=return_length, + return_tensors=None, # We convert the whole batch to tensors at the end + prepend_batch_axis=False, + verbose=verbose, + ) + + for key, value in outputs.items(): + if key not in batch_outputs: + batch_outputs[key] = [] + batch_outputs[key].append(value) + + batch_outputs = self.pad( + batch_outputs, + padding=padding_strategy.value, + max_length=max_length, + pad_to_multiple_of=pad_to_multiple_of, + padding_side=padding_side, + return_attention_mask=return_attention_mask, + ) + + # Remove overflow-related keys before tensor conversion if return_tensors is set + # Slow tokenizers don't support returning these as tensors + if return_tensors and return_overflowing_tokens: + batch_outputs.pop("overflowing_tokens", None) + batch_outputs.pop("num_truncated_tokens", None) + + batch_outputs = BatchEncoding(batch_outputs, tensor_type=return_tensors) + + return batch_outputs + + def _convert_token_to_id(self, token): + """Converts a token (str) in an id using the vocab.""" + return self.vocab.get(token, self.vocab.get(self.unk_token)) + + def _convert_token_to_shape_id(self, token): + """Converts a token (str) in an shape_id using the shape vocab.""" + return self.word_shape.get(token, self.word_shape.get(self.unk_token)) + + def convert_tokens_to_shape_ids(self, tokens: str | list[str]) -> int | list[int]: + if tokens is None: + return None + + ids = [] + for token in tokens: + ids.append(self._convert_token_to_shape_id(token)) + return ids + + def _convert_token_to_pronunciation_id(self, token): + """Converts a token (str) in an shape_id using the shape vocab.""" + return self.word_pronunciation.get(token, self.word_pronunciation.get(self.unk_token)) + + def convert_tokens_to_pronunciation_ids(self, tokens: str | list[str]) -> int | list[int]: + if tokens is None: + return None + + ids = [] + for token in tokens: + ids.append(self._convert_token_to_pronunciation_id(token)) + return ids + + def _convert_id_to_token(self, index): + """Converts an index (integer) in a token (str) using the vocab.""" + return self.ids_to_tokens.get(index, self.unk_token) + + def convert_tokens_to_string(self, tokens): + """Converts a sequence of tokens (string) in a single string.""" + out_string = " ".join(tokens).replace(" ##", "").strip() + return out_string + + def build_inputs_with_special_tokens( + self, + token_ids_0: list[int], + token_ids_1: list[int] | None = None, + cls_token_id: int | None = None, + sep_token_id: int | None = None, + ) -> list[int]: + """ + Build model inputs from a sequence or a pair of sequence for sequence classification tasks by concatenating and + adding special tokens. A BERT sequence has the following format: + + - single sequence: `[CLS] X [SEP]` + - pair of sequences: `[CLS] A [SEP] B [SEP]` + + Args: + token_ids_0 (`List[int]`): + List of IDs to which the special tokens will be added. + token_ids_1 (`List[int]`, *optional*): + Optional second list of IDs for sequence pairs. + + Returns: + `List[int]`: List of [input IDs](../glossary#input-ids) with the appropriate special tokens. + """ + cls = [self.cls_token_id] if cls_token_id is None else [cls_token_id] + sep = [self.sep_token_id] if sep_token_id is None else [sep_token_id] + if token_ids_1 is None: + return cls + token_ids_0 + sep + return cls + token_ids_0 + sep + token_ids_1 + sep + + def get_special_tokens_mask( + self, token_ids_0: list[int], token_ids_1: list[int] | None = None, already_has_special_tokens: bool = False + ) -> list[int]: + """ + Retrieve sequence ids from a token list that has no special tokens added. This method is called when adding + special tokens using the tokenizer `prepare_for_model` method. + + Args: + token_ids_0 (`List[int]`): + List of IDs. + token_ids_1 (`List[int]`, *optional*): + Optional second list of IDs for sequence pairs. + already_has_special_tokens (`bool`, *optional*, defaults to `False`): + Whether or not the token list is already formatted with special tokens for the model. + + Returns: + `List[int]`: A list of integers in the range [0, 1]: 1 for a special token, 0 for a sequence token. + """ + + if already_has_special_tokens: + return super().get_special_tokens_mask( + token_ids_0=token_ids_0, token_ids_1=token_ids_1, already_has_special_tokens=True + ) + + if token_ids_1 is not None: + return [1] + ([0] * len(token_ids_0)) + [1] + ([0] * len(token_ids_1)) + [1] + return [1] + ([0] * len(token_ids_0)) + [1] + + def save_vocabulary(self, save_directory: str, filename_prefix: str | None = None) -> tuple[str, str, str]: + index = 0 + if os.path.isdir(save_directory): + vocab_file = os.path.join( + save_directory, + (filename_prefix + "-" if filename_prefix else "") + self.vocab_files_names["vocab_file"], + ) + word_shape_file = os.path.join( + save_directory, + (filename_prefix + "-" if filename_prefix else "") + self.vocab_files_names["word_shape_file"], + ) + word_pronunciation_file = os.path.join( + save_directory, + (filename_prefix + "-" if filename_prefix else "") + self.vocab_files_names["word_pronunciation_file"], + ) + else: + raise ValueError( + f"Can't find a directory at path '{save_directory}'. To load the vocabulary from a Google " + "pretrained model use `tokenizer = RoCBertTokenizer.from_pretrained(PRETRAINED_MODEL_NAME)`" + ) + + with open(vocab_file, "w", encoding="utf-8") as writer: + for token, token_index in sorted(self.vocab.items(), key=lambda kv: kv[1]): + if index != token_index: + logger.warning( + f"Saving vocabulary to {vocab_file}: vocabulary indices are not consecutive." + " Please check that the vocabulary is not corrupted!" + ) + index = token_index + writer.write(token + "\n") + index += 1 + + with open(word_shape_file, "w", encoding="utf8") as writer: + json.dump(self.word_shape, writer, ensure_ascii=False, indent=4, separators=(", ", ": ")) + + with open(word_pronunciation_file, "w", encoding="utf8") as writer: + json.dump(self.word_pronunciation, writer, ensure_ascii=False, indent=4, separators=(", ", ": ")) + + return ( + vocab_file, + word_shape_file, + word_pronunciation_file, + ) + + +class RoCBertBasicTokenizer: + """ + Constructs a RoCBertBasicTokenizer that will run basic tokenization (punctuation splitting, lower casing, etc.). + + Args: + do_lower_case (`bool`, *optional*, defaults to `True`): + Whether or not to lowercase the input when tokenizing. + never_split (`Iterable`, *optional*): + Collection of tokens which will never be split during tokenization. Only has an effect when + `do_basic_tokenize=True` + tokenize_chinese_chars (`bool`, *optional*, defaults to `True`): + Whether or not to tokenize Chinese characters. + + This should likely be deactivated for Japanese (see this + [issue](https://github.com/huggingface/transformers/issues/328)). + strip_accents (`bool`, *optional*): + Whether or not to strip all accents. If this option is not specified, then it will be determined by the + value for `lowercase` (as in the original BERT). + do_split_on_punc (`bool`, *optional*, defaults to `True`): + In some instances we want to skip the basic punctuation splitting so that later tokenization can capture + the full context of the words, such as contractions. + """ + + def __init__( + self, + do_lower_case=True, + never_split=None, + tokenize_chinese_chars=True, + strip_accents=None, + do_split_on_punc=True, + ): + if never_split is None: + never_split = [] + self.do_lower_case = do_lower_case + self.never_split = set(never_split) + self.tokenize_chinese_chars = tokenize_chinese_chars + self.strip_accents = strip_accents + self.do_split_on_punc = do_split_on_punc + + def tokenize(self, text, never_split=None): + """ + Basic Tokenization of a piece of text. For sub-word tokenization, see WordPieceTokenizer. + + Args: + never_split (`List[str]`, *optional*) + Kept for backward compatibility purposes. Now implemented directly at the base class level (see + [`PreTrainedTokenizer.tokenize`]) List of token not to split. + """ + # union() returns a new set by concatenating the two sets. + never_split = self.never_split.union(set(never_split)) if never_split else self.never_split + text = self._clean_text(text) + + # This was added on November 1st, 2018 for the multilingual and Chinese + # models. This is also applied to the English models now, but it doesn't + # matter since the English models were not trained on any Chinese data + # and generally don't have any Chinese data in them (there are Chinese + # characters in the vocabulary because Wikipedia does have some Chinese + # words in the English Wikipedia.). + if self.tokenize_chinese_chars: + text = self._tokenize_chinese_chars(text) + # prevents treating the same character with different unicode codepoints as different characters + unicode_normalized_text = unicodedata.normalize("NFC", text) + orig_tokens = whitespace_tokenize(unicode_normalized_text) + split_tokens = [] + for token in orig_tokens: + if token not in never_split: + if self.do_lower_case: + token = token.lower() + if self.strip_accents is not False: + token = self._run_strip_accents(token) + elif self.strip_accents: + token = self._run_strip_accents(token) + split_tokens.extend(self._run_split_on_punc(token, never_split)) + + output_tokens = whitespace_tokenize(" ".join(split_tokens)) + return output_tokens + + def _run_strip_accents(self, text): + """Strips accents from a piece of text.""" + text = unicodedata.normalize("NFD", text) + output = [] + for char in text: + cat = unicodedata.category(char) + if cat == "Mn": + continue + output.append(char) + return "".join(output) + + def _run_split_on_punc(self, text, never_split=None): + """Splits punctuation on a piece of text.""" + if not self.do_split_on_punc or (never_split is not None and text in never_split): + return [text] + chars = list(text) + i = 0 + start_new_word = True + output = [] + while i < len(chars): + char = chars[i] + if _is_punctuation(char): + output.append([char]) + start_new_word = True + else: + if start_new_word: + output.append([]) + start_new_word = False + output[-1].append(char) + i += 1 + + return ["".join(x) for x in output] + + def _tokenize_chinese_chars(self, text): + """Adds whitespace around any CJK character.""" + output = [] + for char in text: + cp = ord(char) + if self._is_chinese_char(cp): + output.append(" ") + output.append(char) + output.append(" ") + else: + output.append(char) + return "".join(output) + + def _is_chinese_char(self, cp): + """Checks whether CP is the codepoint of a CJK character.""" + # This defines a "chinese character" as anything in the CJK Unicode block: + # https://en.wikipedia.org/wiki/CJK_Unified_Ideographs_(Unicode_block) + # + # Note that the CJK Unicode block is NOT all Japanese and Korean characters, + # despite its name. The modern Korean Hangul alphabet is a different block, + # as is Japanese Hiragana and Katakana. Those alphabets are used to write + # space-separated words, so they are not treated specially and handled + # like the all of the other languages. + if ( + (cp >= 0x4E00 and cp <= 0x9FFF) + or (cp >= 0x3400 and cp <= 0x4DBF) + or (cp >= 0x20000 and cp <= 0x2A6DF) + or (cp >= 0x2A700 and cp <= 0x2B73F) + or (cp >= 0x2B740 and cp <= 0x2B81F) + or (cp >= 0x2B820 and cp <= 0x2CEAF) + or (cp >= 0xF900 and cp <= 0xFAFF) + or (cp >= 0x2F800 and cp <= 0x2FA1F) + ): + return True + + return False + + def _clean_text(self, text): + """Performs invalid character removal and whitespace cleanup on text.""" + output = [] + for char in text: + cp = ord(char) + if cp == 0 or cp == 0xFFFD or _is_control(char): + continue + if _is_whitespace(char): + output.append(" ") + else: + output.append(char) + return "".join(output) + + +class RoCBertWordpieceTokenizer: + """Runs WordPiece tokenization.""" + + def __init__(self, vocab, unk_token, max_input_chars_per_word=100): + self.vocab = vocab + self.unk_token = unk_token + self.max_input_chars_per_word = max_input_chars_per_word + + def tokenize(self, text): + """ + Tokenizes a piece of text into its word pieces. This uses a greedy longest-match-first algorithm to perform + tokenization using the given vocabulary. + + For example, `input = "unaffable"` will return as output `["un", "##aff", "##able"]`. + + Args: + text: A single token or whitespace separated tokens. This should have + already been passed through *BasicTokenizer*. + + Returns: + A list of wordpiece tokens. + """ + + output_tokens = [] + for token in whitespace_tokenize(text): + chars = list(token) + if len(chars) > self.max_input_chars_per_word: + output_tokens.append(self.unk_token) + continue + + is_bad = False + start = 0 + sub_tokens = [] + while start < len(chars): + end = len(chars) + cur_substr = None + while start < end: + substr = "".join(chars[start:end]) + if start > 0: + substr = "##" + substr + if substr in self.vocab: + cur_substr = substr + break + end -= 1 + if cur_substr is None: + is_bad = True + break + sub_tokens.append(cur_substr) + start = end + + if is_bad: + output_tokens.append(self.unk_token) + else: + output_tokens.extend(sub_tokens) + return output_tokens + + +__all__ = ["RoCBertTokenizer"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/roformer/__init__.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/roformer/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..4d1232523f8ca2c970e91400f2079d4fd44d3511 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/roformer/__init__.py @@ -0,0 +1,29 @@ +# Copyright 2024 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from typing import TYPE_CHECKING + +from ...utils import _LazyModule +from ...utils.import_utils import define_import_structure + + +if TYPE_CHECKING: + from .configuration_roformer import * + from .modeling_roformer import * + from .tokenization_roformer import * + from .tokenization_roformer_fast import * +else: + import sys + + _file = globals()["__file__"] + sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__) diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/roformer/configuration_roformer.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/roformer/configuration_roformer.py new file mode 100644 index 0000000000000000000000000000000000000000..a4b740c1f7042c55c871584a7fe50f157ca65bf8 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/roformer/configuration_roformer.py @@ -0,0 +1,139 @@ +# Copyright 2021 The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""RoFormer model configuration""" + +from ...configuration_utils import PreTrainedConfig +from ...utils import logging + + +logger = logging.get_logger(__name__) + + +class RoFormerConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`RoFormerModel`]. It is used to instantiate an + RoFormer model according to the specified arguments, defining the model architecture. Instantiating a configuration + with the defaults will yield a similar configuration to that of the RoFormer + [junnyu/roformer_chinese_base](https://huggingface.co/junnyu/roformer_chinese_base) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + + Args: + vocab_size (`int`, *optional*, defaults to 50000): + Vocabulary size of the RoFormer model. Defines the number of different tokens that can be represented by + the `inputs_ids` passed when calling [`RoFormerModel`]. + embedding_size (`int`, *optional*, defaults to None): + Dimensionality of the encoder layers and the pooler layer. Defaults to the `hidden_size` if not provided. + hidden_size (`int`, *optional*, defaults to 768): + Dimension of the encoder layers and the pooler layer. + num_hidden_layers (`int`, *optional*, defaults to 12): + Number of hidden layers in the Transformer encoder. + num_attention_heads (`int`, *optional*, defaults to 12): + Number of attention heads for each attention layer in the Transformer encoder. + intermediate_size (`int`, *optional*, defaults to 3072): + Dimension of the "intermediate" (i.e., feed-forward) layer in the Transformer encoder. + hidden_act (`str` or `function`, *optional*, defaults to `"gelu"`): + The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`, + `"relu"`, `"selu"` and `"gelu_new"` are supported. + hidden_dropout_prob (`float`, *optional*, defaults to 0.1): + The dropout probability for all fully connected layers in the embeddings, encoder, and pooler. + attention_probs_dropout_prob (`float`, *optional*, defaults to 0.1): + The dropout ratio for the attention probabilities. + max_position_embeddings (`int`, *optional*, defaults to 1536): + The maximum sequence length that this model might ever be used with. Typically set this to something large + just in case (e.g., 512 or 1024 or 1536). + type_vocab_size (`int`, *optional*, defaults to 2): + The vocabulary size of the `token_type_ids` passed when calling [`RoFormerModel`]. + initializer_range (`float`, *optional*, defaults to 0.02): + The standard deviation of the truncated_normal_initializer for initializing all weight matrices. + layer_norm_eps (`float`, *optional*, defaults to 1e-12): + The epsilon used by the layer normalization layers. + is_decoder (`bool`, *optional*, defaults to `False`): + Whether the model is used as a decoder or not. If `False`, the model is used as an encoder. + use_cache (`bool`, *optional*, defaults to `True`): + Whether or not the model should return the last key/values attentions (not used by all models). Only + relevant if `config.is_decoder=True`. + rotary_value (`bool`, *optional*, defaults to `False`): + Whether or not apply rotary position embeddings on value layer. + + Example: + + ```python + >>> from transformers import RoFormerModel, RoFormerConfig + + >>> # Initializing a RoFormer junnyu/roformer_chinese_base style configuration + >>> configuration = RoFormerConfig() + + >>> # Initializing a model (with random weights) from the junnyu/roformer_chinese_base style configuration + >>> model = RoFormerModel(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "roformer" + + def __init__( + self, + vocab_size=50000, + embedding_size=None, + hidden_size=768, + num_hidden_layers=12, + num_attention_heads=12, + intermediate_size=3072, + hidden_act="gelu", + hidden_dropout_prob=0.1, + attention_probs_dropout_prob=0.1, + max_position_embeddings=1536, + type_vocab_size=2, + initializer_range=0.02, + layer_norm_eps=1e-12, + pad_token_id=0, + bos_token_id=None, + eos_token_id=None, + rotary_value=False, + use_cache=True, + is_decoder=False, + add_cross_attention=False, + tie_word_embeddings=True, + **kwargs, + ): + super().__init__(**kwargs) + self.pad_token_id = pad_token_id + self.bos_token_id = bos_token_id + self.eos_token_id = eos_token_id + self.tie_word_embeddings = tie_word_embeddings + + self.is_decoder = is_decoder + self.add_cross_attention = add_cross_attention + self.vocab_size = vocab_size + self.embedding_size = hidden_size if embedding_size is None else embedding_size + self.hidden_size = hidden_size + self.num_hidden_layers = num_hidden_layers + self.num_attention_heads = num_attention_heads + self.hidden_act = hidden_act + self.intermediate_size = intermediate_size + self.hidden_dropout_prob = hidden_dropout_prob + self.attention_probs_dropout_prob = attention_probs_dropout_prob + self.max_position_embeddings = max_position_embeddings + self.type_vocab_size = type_vocab_size + self.initializer_range = initializer_range + self.layer_norm_eps = layer_norm_eps + self.rotary_value = rotary_value + self.use_cache = use_cache + + +__all__ = ["RoFormerConfig"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/roformer/modeling_roformer.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/roformer/modeling_roformer.py new file mode 100644 index 0000000000000000000000000000000000000000..fb374220a97fdcb533126325598568f7694c0c33 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/roformer/modeling_roformer.py @@ -0,0 +1,1328 @@ +# Copyright 2021 The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""PyTorch RoFormer model.""" + +import math +from collections.abc import Callable + +import numpy as np +import torch +from torch import nn +from torch.nn import BCEWithLogitsLoss, CrossEntropyLoss, MSELoss + +from ... import initialization as init +from ...activations import ACT2FN, get_activation +from ...cache_utils import Cache, DynamicCache, EncoderDecoderCache +from ...generation import GenerationMixin +from ...modeling_layers import GradientCheckpointingLayer +from ...modeling_outputs import ( + BaseModelOutputWithPastAndCrossAttentions, + CausalLMOutputWithCrossAttentions, + MaskedLMOutput, + MultipleChoiceModelOutput, + QuestionAnsweringModelOutput, + SequenceClassifierOutput, + TokenClassifierOutput, +) +from ...modeling_utils import PreTrainedModel +from ...pytorch_utils import apply_chunking_to_forward +from ...utils import auto_docstring, logging +from .configuration_roformer import RoFormerConfig + + +logger = logging.get_logger(__name__) + + +# Copied from transformers.models.marian.modeling_marian.MarianSinusoidalPositionalEmbedding with Marian->RoFormer +class RoFormerSinusoidalPositionalEmbedding(nn.Embedding): + """This module produces sinusoidal positional embeddings of any length.""" + + def __init__(self, num_positions: int, embedding_dim: int, padding_idx: int | None = None) -> None: + super().__init__(num_positions, embedding_dim, _freeze=True) + + def create_weight(self): + """ + Identical to the XLM create_sinusoidal_embeddings except features are not interleaved. The cos features are in + the 2nd half of the vector. [dim // 2:] + """ + n_pos, dim = self.weight.shape + position_enc = np.array( + [[pos / np.power(10000, 2 * (j // 2) / dim) for j in range(dim)] for pos in range(n_pos)] + ) + out = torch.empty(n_pos, dim, dtype=self.weight.dtype, requires_grad=False) + sentinel = dim // 2 if dim % 2 == 0 else (dim // 2) + 1 + out[:, 0:sentinel] = torch.FloatTensor(np.sin(position_enc[:, 0::2])) + out[:, sentinel:] = torch.FloatTensor(np.cos(position_enc[:, 1::2])) + return out + + @torch.no_grad() + def forward( + self, input_ids_shape: torch.Size, past_key_values_length: int = 0, position_ids: torch.Tensor | None = None + ) -> torch.Tensor: + """`input_ids_shape` is expected to be [bsz x seqlen].""" + if position_ids is None: + bsz, seq_len = input_ids_shape[:2] + position_ids = torch.arange( + past_key_values_length, past_key_values_length + seq_len, dtype=torch.long, device=self.weight.device + ) + return super().forward(position_ids) + + +class RoFormerEmbeddings(nn.Module): + """Construct the embeddings from word and token_type embeddings.""" + + def __init__(self, config): + super().__init__() + self.word_embeddings = nn.Embedding(config.vocab_size, config.embedding_size, padding_idx=config.pad_token_id) + self.token_type_embeddings = nn.Embedding(config.type_vocab_size, config.embedding_size) + + self.LayerNorm = nn.LayerNorm(config.embedding_size, eps=config.layer_norm_eps) + self.dropout = nn.Dropout(config.hidden_dropout_prob) + + def forward(self, input_ids=None, token_type_ids=None, inputs_embeds=None): + if input_ids is not None: + input_shape = input_ids.size() + else: + input_shape = inputs_embeds.size()[:-1] + + if inputs_embeds is None: + inputs_embeds = self.word_embeddings(input_ids) + + if token_type_ids is None: + token_type_ids = torch.zeros(input_shape, dtype=torch.long, device=inputs_embeds.device) + + token_type_embeddings = self.token_type_embeddings(token_type_ids) + + embeddings = inputs_embeds + token_type_embeddings + + embeddings = self.LayerNorm(embeddings) + embeddings = self.dropout(embeddings) + return embeddings + + +class RoFormerSelfAttention(nn.Module): + def __init__(self, config, layer_idx=None): + super().__init__() + if config.hidden_size % config.num_attention_heads != 0 and not hasattr(config, "embedding_size"): + raise ValueError( + f"The hidden size ({config.hidden_size}) is not a multiple of the number of attention " + f"heads ({config.num_attention_heads})" + ) + + self.num_attention_heads = config.num_attention_heads + self.attention_head_size = int(config.hidden_size / config.num_attention_heads) + self.all_head_size = self.num_attention_heads * self.attention_head_size + + self.query = nn.Linear(config.hidden_size, self.all_head_size) + self.key = nn.Linear(config.hidden_size, self.all_head_size) + self.value = nn.Linear(config.hidden_size, self.all_head_size) + + self.dropout = nn.Dropout(config.attention_probs_dropout_prob) + + self.is_decoder = config.is_decoder + self.rotary_value = config.rotary_value + self.layer_idx = layer_idx + + def forward( + self, + hidden_states, + attention_mask=None, + sinusoidal_pos=None, + encoder_hidden_states=None, + past_key_values=None, + output_attentions=False, + cache_position=None, + ): + batch_size, seq_length, _ = hidden_states.shape + query_layer = ( + self.query(hidden_states) + .view(batch_size, -1, self.num_attention_heads, self.attention_head_size) + .transpose(1, 2) + ) + # If this is instantiated as a cross-attention module, the keys + # and values come from an encoder; the attention mask needs to be + # such that the encoder's padding tokens are not attended to. + is_cross_attention = encoder_hidden_states is not None + + is_updated = False + if past_key_values is not None: + if isinstance(past_key_values, EncoderDecoderCache): + is_updated = past_key_values.is_updated.get(self.layer_idx) + if is_cross_attention: + # after the first generated id, we can subsequently re-use all key/value_layer from cache + curr_past_key_values = past_key_values.cross_attention_cache + else: + curr_past_key_values = past_key_values.self_attention_cache + else: + curr_past_key_values = past_key_values + + current_states = encoder_hidden_states if is_cross_attention else hidden_states + if is_cross_attention and past_key_values is not None and is_updated: + # reuse k,v, cross_attentions + key_layer = curr_past_key_values.layers[self.layer_idx].keys + value_layer = curr_past_key_values.layers[self.layer_idx].values + else: + key_layer = ( + self.key(current_states) + .view(batch_size, -1, self.num_attention_heads, self.attention_head_size) + .transpose(1, 2) + ) + value_layer = ( + self.value(current_states) + .view(batch_size, -1, self.num_attention_heads, self.attention_head_size) + .transpose(1, 2) + ) + + # Apply RoPE if self attention + if not is_cross_attention and sinusoidal_pos is not None: + if self.rotary_value: + query_layer, key_layer, value_layer = self.apply_rotary_position_embeddings( + sinusoidal_pos, query_layer, key_layer, value_layer + ) + else: + query_layer, key_layer = self.apply_rotary_position_embeddings( + sinusoidal_pos, query_layer, key_layer + ) + + if past_key_values is not None: + # save all key/value_layer to cache to be re-used for fast auto-regressive generation + cache_position = cache_position if not is_cross_attention else None + key_layer, value_layer = curr_past_key_values.update( + key_layer, value_layer, self.layer_idx, {"cache_position": cache_position} + ) + # set flag that curr layer for cross-attn is already updated so we can re-use in subsequent calls + if is_cross_attention and isinstance(past_key_values, EncoderDecoderCache): + past_key_values.is_updated[self.layer_idx] = True + + # Take the dot product between "query" and "key" to get the raw attention scores. + attention_scores = torch.matmul(query_layer, key_layer.transpose(-1, -2)) + + attention_scores = attention_scores / math.sqrt(self.attention_head_size) + if attention_mask is not None: + # Apply the attention mask is (precomputed for all layers in RoFormerModel forward() function) + attention_scores = attention_scores + attention_mask + + # Normalize the attention scores to probabilities. + attention_probs = nn.functional.softmax(attention_scores, dim=-1) + + # This is actually dropping out entire tokens to attend to, which might + # seem a bit unusual, but is taken from the original Transformer paper. + attention_probs = self.dropout(attention_probs) + + context_layer = torch.matmul(attention_probs, value_layer) + + context_layer = context_layer.permute(0, 2, 1, 3).contiguous() + new_context_layer_shape = context_layer.size()[:-2] + (self.all_head_size,) + context_layer = context_layer.view(*new_context_layer_shape) + + return context_layer, attention_probs + + @staticmethod + def apply_rotary_position_embeddings(sinusoidal_pos, query_layer, key_layer, value_layer=None): + # https://kexue.fm/archives/8265 + # sin [batch_size, num_heads, sequence_length, embed_size_per_head//2] + # cos [batch_size, num_heads, sequence_length, embed_size_per_head//2] + sin, cos = sinusoidal_pos.chunk(2, dim=-1) + # sin [θ0,θ1,θ2......θd/2-1] -> sin_pos [θ0,θ0,θ1,θ1,θ2,θ2......θd/2-1,θd/2-1] + sin_pos = torch.stack([sin, sin], dim=-1).reshape_as(sinusoidal_pos) + # cos [θ0,θ1,θ2......θd/2-1] -> cos_pos [θ0,θ0,θ1,θ1,θ2,θ2......θd/2-1,θd/2-1] + cos_pos = torch.stack([cos, cos], dim=-1).reshape_as(sinusoidal_pos) + # rotate_half_query_layer [-q1,q0,-q3,q2......,-qd-1,qd-2] + rotate_half_query_layer = torch.stack([-query_layer[..., 1::2], query_layer[..., ::2]], dim=-1).reshape_as( + query_layer + ) + query_layer = query_layer * cos_pos + rotate_half_query_layer * sin_pos + # rotate_half_key_layer [-k1,k0,-k3,k2......,-kd-1,kd-2] + rotate_half_key_layer = torch.stack([-key_layer[..., 1::2], key_layer[..., ::2]], dim=-1).reshape_as(key_layer) + key_layer = key_layer * cos_pos + rotate_half_key_layer * sin_pos + if value_layer is not None: + # rotate_half_value_layer [-v1,v0,-v3,v2......,-vd-1,vd-2] + rotate_half_value_layer = torch.stack([-value_layer[..., 1::2], value_layer[..., ::2]], dim=-1).reshape_as( + value_layer + ) + value_layer = value_layer * cos_pos + rotate_half_value_layer * sin_pos + return query_layer, key_layer, value_layer + return query_layer, key_layer + + +# Copied from transformers.models.bert.modeling_bert.BertSelfOutput with Bert->RoFormer +class RoFormerSelfOutput(nn.Module): + def __init__(self, config): + super().__init__() + self.dense = nn.Linear(config.hidden_size, config.hidden_size) + self.LayerNorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps) + self.dropout = nn.Dropout(config.hidden_dropout_prob) + + def forward(self, hidden_states: torch.Tensor, input_tensor: torch.Tensor) -> torch.Tensor: + hidden_states = self.dense(hidden_states) + hidden_states = self.dropout(hidden_states) + hidden_states = self.LayerNorm(hidden_states + input_tensor) + return hidden_states + + +class RoFormerAttention(nn.Module): + def __init__(self, config, layer_idx=None): + super().__init__() + self.self = RoFormerSelfAttention(config, layer_idx=layer_idx) + self.output = RoFormerSelfOutput(config) + + def forward( + self, + hidden_states, + attention_mask=None, + sinusoidal_pos=None, + encoder_hidden_states=None, + past_key_values=None, + output_attentions=False, + cache_position=None, + ): + self_outputs = self.self( + hidden_states, + attention_mask=attention_mask, + sinusoidal_pos=sinusoidal_pos, + encoder_hidden_states=encoder_hidden_states, + past_key_values=past_key_values, + output_attentions=output_attentions, + cache_position=cache_position, + ) + attention_output = self.output(self_outputs[0], hidden_states) + outputs = (attention_output,) + self_outputs[1:] # add attentions if we output them + return outputs + + +# Copied from transformers.models.bert.modeling_bert.BertIntermediate with Bert->RoFormer +class RoFormerIntermediate(nn.Module): + def __init__(self, config): + super().__init__() + self.dense = nn.Linear(config.hidden_size, config.intermediate_size) + if isinstance(config.hidden_act, str): + self.intermediate_act_fn = ACT2FN[config.hidden_act] + else: + self.intermediate_act_fn = config.hidden_act + + def forward(self, hidden_states: torch.Tensor) -> torch.Tensor: + hidden_states = self.dense(hidden_states) + hidden_states = self.intermediate_act_fn(hidden_states) + return hidden_states + + +# Copied from transformers.models.bert.modeling_bert.BertOutput with Bert->RoFormer +class RoFormerOutput(nn.Module): + def __init__(self, config): + super().__init__() + self.dense = nn.Linear(config.intermediate_size, config.hidden_size) + self.LayerNorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps) + self.dropout = nn.Dropout(config.hidden_dropout_prob) + + def forward(self, hidden_states: torch.Tensor, input_tensor: torch.Tensor) -> torch.Tensor: + hidden_states = self.dense(hidden_states) + hidden_states = self.dropout(hidden_states) + hidden_states = self.LayerNorm(hidden_states + input_tensor) + return hidden_states + + +class RoFormerLayer(GradientCheckpointingLayer): + def __init__(self, config, layer_idx=None): + super().__init__() + self.chunk_size_feed_forward = config.chunk_size_feed_forward + self.seq_len_dim = 1 + self.attention = RoFormerAttention(config, layer_idx) + self.is_decoder = config.is_decoder + self.add_cross_attention = config.add_cross_attention + if self.add_cross_attention: + if not self.is_decoder: + raise ValueError(f"{self} should be used as a decoder model if cross attention is added") + self.crossattention = RoFormerAttention(config, layer_idx) + self.intermediate = RoFormerIntermediate(config) + self.output = RoFormerOutput(config) + + def forward( + self, + hidden_states, + attention_mask=None, + sinusoidal_pos=None, + encoder_hidden_states=None, + encoder_attention_mask=None, + past_key_values=None, + output_attentions=False, + cache_position=None, + ): + self_attention_outputs = self.attention( + hidden_states, + attention_mask=attention_mask, + sinusoidal_pos=sinusoidal_pos, + output_attentions=output_attentions, + past_key_values=past_key_values, + cache_position=cache_position, + ) + attention_output = self_attention_outputs[0] + outputs = self_attention_outputs[1:] # add self attentions if we output attention weights + + if self.is_decoder and encoder_hidden_states is not None: + if not hasattr(self, "crossattention"): + raise ValueError( + f"If `encoder_hidden_states` are passed, {self} has to be instantiated with cross-attention " + "layers by setting `config.add_cross_attention=True`" + ) + + cross_attention_outputs = self.crossattention( + attention_output, + attention_mask=encoder_attention_mask, + sinusoidal_pos=sinusoidal_pos, + encoder_hidden_states=encoder_hidden_states, + past_key_values=past_key_values, + output_attentions=output_attentions, + cache_position=cache_position, + ) + attention_output = cross_attention_outputs[0] + outputs = outputs + cross_attention_outputs[1:] # add cross attentions if we output attention weights + + layer_output = apply_chunking_to_forward( + self.feed_forward_chunk, self.chunk_size_feed_forward, self.seq_len_dim, attention_output + ) + return (layer_output,) + outputs + + def feed_forward_chunk(self, attention_output): + intermediate_output = self.intermediate(attention_output) + layer_output = self.output(intermediate_output, attention_output) + return layer_output + + +class RoFormerEncoder(nn.Module): + def __init__(self, config): + super().__init__() + self.config = config + self.embed_positions = RoFormerSinusoidalPositionalEmbedding( + config.max_position_embeddings, config.hidden_size // config.num_attention_heads + ) + self.layer = nn.ModuleList([RoFormerLayer(config, layer_idx=i) for i in range(config.num_hidden_layers)]) + self.gradient_checkpointing = False + + def forward( + self, + hidden_states, + attention_mask=None, + encoder_hidden_states=None, + encoder_attention_mask=None, + past_key_values=None, + use_cache=None, + output_attentions=False, + output_hidden_states=False, + return_dict=True, + cache_position=None, + ): + if self.gradient_checkpointing and self.training: + if use_cache: + logger.warning_once( + "`use_cache=True` is incompatible with gradient checkpointing. Setting `use_cache=False`..." + ) + use_cache = False + + all_hidden_states = () if output_hidden_states else None + all_self_attentions = () if output_attentions else None + all_cross_attentions = () if output_attentions and self.config.add_cross_attention else None + + past_key_values_length = past_key_values.get_seq_length() if past_key_values is not None else 0 + + # [sequence_length, embed_size_per_head] -> [batch_size, num_heads, sequence_length, embed_size_per_head] + sinusoidal_pos = self.embed_positions(hidden_states.shape[:-1], past_key_values_length)[None, None, :, :] + + for i, layer_module in enumerate(self.layer): + if output_hidden_states: + all_hidden_states = all_hidden_states + (hidden_states,) + + layer_outputs = layer_module( + hidden_states, + attention_mask, + sinusoidal_pos, + encoder_hidden_states, + encoder_attention_mask, + past_key_values, + output_attentions, + cache_position, + ) + + hidden_states = layer_outputs[0] + if output_attentions: + all_self_attentions = all_self_attentions + (layer_outputs[1],) + if self.config.add_cross_attention: + all_cross_attentions = all_cross_attentions + (layer_outputs[2],) + + if output_hidden_states: + all_hidden_states = all_hidden_states + (hidden_states,) + + if not return_dict: + return tuple( + v + for v in [ + hidden_states, + past_key_values, + all_hidden_states, + all_self_attentions, + all_cross_attentions, + ] + if v is not None + ) + return BaseModelOutputWithPastAndCrossAttentions( + last_hidden_state=hidden_states, + past_key_values=past_key_values, + hidden_states=all_hidden_states, + attentions=all_self_attentions, + cross_attentions=all_cross_attentions, + ) + + +# Copied from transformers.models.xlm.modeling_xlm.XLMSequenceSummary with XLM->RoFormer +class RoFormerSequenceSummary(nn.Module): + r""" + Compute a single vector summary of a sequence hidden states. + + Args: + config ([`RoFormerConfig`]): + The config used by the model. Relevant arguments in the config class of the model are (refer to the actual + config class of your model for the default values it uses): + + - **summary_type** (`str`) -- The method to use to make this summary. Accepted values are: + + - `"last"` -- Take the last token hidden state (like XLNet) + - `"first"` -- Take the first token hidden state (like Bert) + - `"mean"` -- Take the mean of all tokens hidden states + - `"cls_index"` -- Supply a Tensor of classification token position (GPT/GPT-2) + - `"attn"` -- Not implemented now, use multi-head attention + + - **summary_use_proj** (`bool`) -- Add a projection after the vector extraction. + - **summary_proj_to_labels** (`bool`) -- If `True`, the projection outputs to `config.num_labels` classes + (otherwise to `config.hidden_size`). + - **summary_activation** (`Optional[str]`) -- Set to `"tanh"` to add a tanh activation to the output, + another string or `None` will add no activation. + - **summary_first_dropout** (`float`) -- Optional dropout probability before the projection and activation. + - **summary_last_dropout** (`float`)-- Optional dropout probability after the projection and activation. + """ + + def __init__(self, config: RoFormerConfig): + super().__init__() + + self.summary_type = getattr(config, "summary_type", "last") + if self.summary_type == "attn": + # We should use a standard multi-head attention module with absolute positional embedding for that. + # Cf. https://github.com/zihangdai/xlnet/blob/master/modeling.py#L253-L276 + # We can probably just use the multi-head attention module of PyTorch >=1.1.0 + raise NotImplementedError + + self.summary = nn.Identity() + if hasattr(config, "summary_use_proj") and config.summary_use_proj: + if hasattr(config, "summary_proj_to_labels") and config.summary_proj_to_labels and config.num_labels > 0: + num_classes = config.num_labels + else: + num_classes = config.hidden_size + self.summary = nn.Linear(config.hidden_size, num_classes) + + activation_string = getattr(config, "summary_activation", None) + self.activation: Callable = get_activation(activation_string) if activation_string else nn.Identity() + + self.first_dropout = nn.Identity() + if hasattr(config, "summary_first_dropout") and config.summary_first_dropout > 0: + self.first_dropout = nn.Dropout(config.summary_first_dropout) + + self.last_dropout = nn.Identity() + if hasattr(config, "summary_last_dropout") and config.summary_last_dropout > 0: + self.last_dropout = nn.Dropout(config.summary_last_dropout) + + def forward( + self, hidden_states: torch.FloatTensor, cls_index: torch.LongTensor | None = None + ) -> torch.FloatTensor: + """ + Compute a single vector summary of a sequence hidden states. + + Args: + hidden_states (`torch.FloatTensor` of shape `[batch_size, seq_len, hidden_size]`): + The hidden states of the last layer. + cls_index (`torch.LongTensor` of shape `[batch_size]` or `[batch_size, ...]` where ... are optional leading dimensions of `hidden_states`, *optional*): + Used if `summary_type == "cls_index"` and takes the last token of the sequence as classification token. + + Returns: + `torch.FloatTensor`: The summary of the sequence hidden states. + """ + if self.summary_type == "last": + output = hidden_states[:, -1] + elif self.summary_type == "first": + output = hidden_states[:, 0] + elif self.summary_type == "mean": + output = hidden_states.mean(dim=1) + elif self.summary_type == "cls_index": + if cls_index is None: + cls_index = torch.full_like( + hidden_states[..., :1, :], + hidden_states.shape[-2] - 1, + dtype=torch.long, + ) + else: + cls_index = cls_index.unsqueeze(-1).unsqueeze(-1) + cls_index = cls_index.expand((-1,) * (cls_index.dim() - 1) + (hidden_states.size(-1),)) + # shape of cls_index: (bsz, XX, 1, hidden_size) where XX are optional leading dim of hidden_states + output = hidden_states.gather(-2, cls_index).squeeze(-2) # shape (bsz, XX, hidden_size) + elif self.summary_type == "attn": + raise NotImplementedError + + output = self.first_dropout(output) + output = self.summary(output) + output = self.activation(output) + output = self.last_dropout(output) + + return output + + +class RoFormerPredictionHeadTransform(nn.Module): + def __init__(self, config): + super().__init__() + self.dense = nn.Linear(config.hidden_size, config.embedding_size) + if isinstance(config.hidden_act, str): + self.transform_act_fn = ACT2FN[config.hidden_act] + else: + self.transform_act_fn = config.hidden_act + self.LayerNorm = nn.LayerNorm(config.embedding_size, eps=config.layer_norm_eps) + + def forward(self, hidden_states): + hidden_states = self.dense(hidden_states) + hidden_states = self.transform_act_fn(hidden_states) + hidden_states = self.LayerNorm(hidden_states) + return hidden_states + + +class RoFormerLMPredictionHead(nn.Module): + def __init__(self, config): + super().__init__() + self.transform = RoFormerPredictionHeadTransform(config) + + # The output weights are the same as the input embeddings, but there is + # an output-only bias for each token. + self.decoder = nn.Linear(config.embedding_size, config.vocab_size, bias=True) + + self.bias = nn.Parameter(torch.zeros(config.vocab_size)) + + def forward(self, hidden_states): + hidden_states = self.transform(hidden_states) + hidden_states = self.decoder(hidden_states) + return hidden_states + + +# Copied from transformers.models.bert.modeling_bert.BertOnlyMLMHead with Bert->RoFormer +class RoFormerOnlyMLMHead(nn.Module): + def __init__(self, config): + super().__init__() + self.predictions = RoFormerLMPredictionHead(config) + + def forward(self, sequence_output: torch.Tensor) -> torch.Tensor: + prediction_scores = self.predictions(sequence_output) + return prediction_scores + + +@auto_docstring +class RoFormerPreTrainedModel(PreTrainedModel): + config: RoFormerConfig + base_model_prefix = "roformer" + supports_gradient_checkpointing = True + + @torch.no_grad() + def _init_weights(self, module): + super()._init_weights(module) + if isinstance(module, RoFormerSinusoidalPositionalEmbedding): + init.copy_(module.weight, module.create_weight()) + elif isinstance(module, RoFormerLMPredictionHead): + init.zeros_(module.bias) + + +@auto_docstring( + custom_intro=""" + + The model can behave as an encoder (with only self-attention) as well as a decoder, in which case a layer of + cross-attention is added between the self-attention layers, following the architecture described in [Attention is + all you need](https://huggingface.co/papers/1706.03762) by Ashish Vaswani, Noam Shazeer, Niki Parmar, Jakob Uszkoreit, + Llion Jones, Aidan N. Gomez, Lukasz Kaiser and Illia Polosukhin. + + To behave as an decoder the model needs to be initialized with the `is_decoder` argument of the configuration set + to `True`. To be used in a Seq2Seq model, the model needs to initialized with both `is_decoder` argument and + `add_cross_attention` set to `True`; an `encoder_hidden_states` is then expected as an input to the forward pass. + """ +) +class RoFormerModel(RoFormerPreTrainedModel): + def __init__(self, config): + super().__init__(config) + self.config = config + self.embeddings = RoFormerEmbeddings(config) + + if config.embedding_size != config.hidden_size: + self.embeddings_project = nn.Linear(config.embedding_size, config.hidden_size) + + self.encoder = RoFormerEncoder(config) + + # Initialize weights and apply final processing + self.post_init() + + def get_input_embeddings(self): + return self.embeddings.word_embeddings + + def set_input_embeddings(self, value): + self.embeddings.word_embeddings = value + + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.FloatTensor | None = None, + token_type_ids: torch.LongTensor | None = None, + inputs_embeds: torch.FloatTensor | None = None, + encoder_hidden_states: torch.FloatTensor | None = None, + encoder_attention_mask: torch.FloatTensor | None = None, + past_key_values: Cache | None = None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + cache_position: torch.Tensor | None = None, + **kwargs, + ) -> BaseModelOutputWithPastAndCrossAttentions | tuple[torch.Tensor]: + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + if self.config.is_decoder: + use_cache = use_cache if use_cache is not None else self.config.use_cache + else: + use_cache = False + + if input_ids is not None and inputs_embeds is not None: + raise ValueError("You cannot specify both input_ids and inputs_embeds at the same time") + elif input_ids is not None: + self.warn_if_padding_and_no_attention_mask(input_ids, attention_mask) + input_shape = input_ids.size() + elif inputs_embeds is not None: + input_shape = inputs_embeds.size()[:-1] + else: + raise ValueError("You have to specify either input_ids or inputs_embeds") + + batch_size, seq_length = input_shape + device = input_ids.device if input_ids is not None else inputs_embeds.device + + if use_cache and past_key_values is None: + past_key_values = ( + EncoderDecoderCache(DynamicCache(config=self.config), DynamicCache(config=self.config)) + if encoder_hidden_states is not None or self.config.is_encoder_decoder + else DynamicCache(config=self.config) + ) + + past_key_values_length = 0 if past_key_values is None else past_key_values.get_seq_length() + + if attention_mask is None: + attention_mask = torch.ones(((batch_size, seq_length + past_key_values_length)), device=device) + if token_type_ids is None: + token_type_ids = torch.zeros(input_shape, dtype=torch.long, device=device) + + # We can provide a self-attention mask of dimensions [batch_size, from_seq_length, to_seq_length] + # ourselves in which case we just need to make it broadcastable to all heads. + extended_attention_mask: torch.Tensor = self.get_extended_attention_mask(attention_mask, input_shape) + + # If a 2D or 3D attention mask is provided for the cross-attention + # we need to make broadcastable to [batch_size, num_heads, seq_length, seq_length] + if self.config.is_decoder and encoder_hidden_states is not None: + encoder_batch_size, encoder_sequence_length, _ = encoder_hidden_states.size() + encoder_hidden_shape = (encoder_batch_size, encoder_sequence_length) + if encoder_attention_mask is None: + encoder_attention_mask = torch.ones(encoder_hidden_shape, device=device) + encoder_extended_attention_mask = self.invert_attention_mask(encoder_attention_mask) + else: + encoder_extended_attention_mask = None + + embedding_output = self.embeddings( + input_ids=input_ids, token_type_ids=token_type_ids, inputs_embeds=inputs_embeds + ) + if hasattr(self, "embeddings_project"): + embedding_output = self.embeddings_project(embedding_output) + + encoder_outputs = self.encoder( + embedding_output, + attention_mask=extended_attention_mask, + encoder_hidden_states=encoder_hidden_states, + encoder_attention_mask=encoder_extended_attention_mask, + past_key_values=past_key_values, + use_cache=use_cache, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + cache_position=cache_position, + ) + sequence_output = encoder_outputs[0] + + if not return_dict: + return (sequence_output,) + encoder_outputs[1:] + + return BaseModelOutputWithPastAndCrossAttentions( + last_hidden_state=sequence_output, + past_key_values=encoder_outputs.past_key_values, + hidden_states=encoder_outputs.hidden_states, + attentions=encoder_outputs.attentions, + cross_attentions=encoder_outputs.cross_attentions, + ) + + +@auto_docstring +class RoFormerForMaskedLM(RoFormerPreTrainedModel): + _tied_weights_keys = { + "cls.predictions.decoder.bias": "cls.predictions.bias", + "cls.predictions.decoder.weight": "roformer.embeddings.word_embeddings.weight", + } + + def __init__(self, config): + super().__init__(config) + + if config.is_decoder: + logger.warning( + "If you want to use `RoFormerForMaskedLM` make sure `config.is_decoder=False` for " + "bi-directional self-attention." + ) + + self.roformer = RoFormerModel(config) + self.cls = RoFormerOnlyMLMHead(config) + + # Initialize weights and apply final processing + self.post_init() + + def get_output_embeddings(self): + return self.cls.predictions.decoder + + def set_output_embeddings(self, new_embeddings): + self.cls.predictions.decoder = new_embeddings + self.cls.predictions.bias = new_embeddings.bias + + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.FloatTensor | None = None, + token_type_ids: torch.LongTensor | None = None, + inputs_embeds: torch.FloatTensor | None = None, + encoder_hidden_states: torch.FloatTensor | None = None, + encoder_attention_mask: torch.FloatTensor | None = None, + labels: torch.LongTensor | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + **kwargs, + ) -> MaskedLMOutput | tuple[torch.Tensor]: + r""" + labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Labels for computing the masked language modeling loss. Indices should be in `[-100, 0, ..., + config.vocab_size]` (see `input_ids` docstring) Tokens with indices set to `-100` are ignored (masked), the + loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]`. + """ + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + outputs = self.roformer( + input_ids, + attention_mask=attention_mask, + token_type_ids=token_type_ids, + inputs_embeds=inputs_embeds, + encoder_hidden_states=encoder_hidden_states, + encoder_attention_mask=encoder_attention_mask, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + + sequence_output = outputs[0] + prediction_scores = self.cls(sequence_output) + + masked_lm_loss = None + if labels is not None: + loss_fct = CrossEntropyLoss() # -100 index = padding token + masked_lm_loss = loss_fct(prediction_scores.view(-1, self.config.vocab_size), labels.view(-1)) + + if not return_dict: + output = (prediction_scores,) + outputs[1:] + return ((masked_lm_loss,) + output) if masked_lm_loss is not None else output + + return MaskedLMOutput( + loss=masked_lm_loss, + logits=prediction_scores, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + ) + + +@auto_docstring( + custom_intro=""" + RoFormer Model with a `language modeling` head on top for CLM fine-tuning. + """ +) +class RoFormerForCausalLM(RoFormerPreTrainedModel, GenerationMixin): + _tied_weights_keys = { + "cls.predictions.decoder.bias": "cls.predictions.bias", + "cls.predictions.decoder.weight": "roformer.embeddings.word_embeddings.weight", + } + + def __init__(self, config): + super().__init__(config) + + if not config.is_decoder: + logger.warning("If you want to use `RoFormerForCausalLM` as a standalone, add `is_decoder=True.`") + + self.roformer = RoFormerModel(config) + self.cls = RoFormerOnlyMLMHead(config) + + # Initialize weights and apply final processing + self.post_init() + + def get_output_embeddings(self): + return self.cls.predictions.decoder + + def set_output_embeddings(self, new_embeddings): + self.cls.predictions.decoder = new_embeddings + self.cls.predictions.bias = new_embeddings.bias + + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.FloatTensor | None = None, + token_type_ids: torch.LongTensor | None = None, + inputs_embeds: torch.FloatTensor | None = None, + encoder_hidden_states: torch.FloatTensor | None = None, + encoder_attention_mask: torch.FloatTensor | None = None, + past_key_values: Cache | None = None, + labels: torch.LongTensor | None = None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + cache_position: torch.Tensor | None = None, + logits_to_keep: int | torch.Tensor = 0, + **kwargs, + ) -> CausalLMOutputWithCrossAttentions | tuple[torch.Tensor]: + r""" + labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Labels for computing the left-to-right language modeling loss (next word prediction). Indices should be in + `[-100, 0, ..., config.vocab_size]` (see `input_ids` docstring) Tokens with indices set to `-100` are + ignored (masked), the loss is only computed for the tokens with labels n `[0, ..., config.vocab_size]`. + + Example: + + ```python + >>> from transformers import AutoTokenizer, RoFormerForCausalLM, RoFormerConfig + >>> import torch + + >>> tokenizer = AutoTokenizer.from_pretrained("junnyu/roformer_chinese_base") + >>> config = RoFormerConfig.from_pretrained("junnyu/roformer_chinese_base") + >>> config.is_decoder = True + >>> model = RoFormerForCausalLM.from_pretrained("junnyu/roformer_chinese_base", config=config) + + >>> inputs = tokenizer("今天天气非常好。", return_tensors="pt") + >>> outputs = model(**inputs) + + >>> prediction_logits = outputs.logits + ```""" + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + outputs = self.roformer( + input_ids, + attention_mask=attention_mask, + token_type_ids=token_type_ids, + inputs_embeds=inputs_embeds, + encoder_hidden_states=encoder_hidden_states, + encoder_attention_mask=encoder_attention_mask, + past_key_values=past_key_values, + use_cache=use_cache, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + cache_position=cache_position, + ) + + hidden_states = outputs[0] + # Only compute necessary logits, and do not upcast them to float if we are not computing the loss + slice_indices = slice(-logits_to_keep, None) if isinstance(logits_to_keep, int) else logits_to_keep + logits = self.cls(hidden_states[:, slice_indices, :]) + + loss = None + if labels is not None: + loss = self.loss_function(logits=logits, labels=labels, vocab_size=self.config.vocab_size, **kwargs) + + if not return_dict: + output = (logits,) + outputs[1:] + return ((loss,) + output) if loss is not None else output + + return CausalLMOutputWithCrossAttentions( + loss=loss, + logits=logits, + past_key_values=outputs.past_key_values, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + cross_attentions=outputs.cross_attentions, + ) + + +class RoFormerClassificationHead(nn.Module): + """Head for sentence-level classification tasks.""" + + def __init__(self, config): + super().__init__() + self.dense = nn.Linear(config.hidden_size, config.hidden_size) + self.dropout = nn.Dropout(config.hidden_dropout_prob) + self.out_proj = nn.Linear(config.hidden_size, config.num_labels) + + self.config = config + + def forward(self, features, **kwargs): + x = features[:, 0, :] # take token (equiv. to [CLS]) + x = self.dropout(x) + x = self.dense(x) + x = ACT2FN[self.config.hidden_act](x) + x = self.dropout(x) + x = self.out_proj(x) + return x + + +@auto_docstring( + custom_intro=""" + RoFormer Model transformer with a sequence classification/regression head on top (a linear layer on top of the + pooled output) e.g. for GLUE tasks. + """ +) +class RoFormerForSequenceClassification(RoFormerPreTrainedModel): + def __init__(self, config): + super().__init__(config) + self.num_labels = config.num_labels + self.roformer = RoFormerModel(config) + self.classifier = RoFormerClassificationHead(config) + + # Initialize weights and apply final processing + self.post_init() + + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.FloatTensor | None = None, + token_type_ids: torch.LongTensor | None = None, + inputs_embeds: torch.FloatTensor | None = None, + labels: torch.LongTensor | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + **kwargs, + ) -> SequenceClassifierOutput | tuple[torch.Tensor]: + r""" + labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*): + Labels for computing the sequence classification/regression loss. Indices should be in `[0, ..., + config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If + `config.num_labels > 1` a classification loss is computed (Cross-Entropy). + """ + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + outputs = self.roformer( + input_ids, + attention_mask=attention_mask, + token_type_ids=token_type_ids, + inputs_embeds=inputs_embeds, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + + sequence_output = outputs[0] + logits = self.classifier(sequence_output) + + loss = None + if labels is not None: + if self.config.problem_type is None: + if self.num_labels == 1: + self.config.problem_type = "regression" + elif self.num_labels > 1 and (labels.dtype == torch.long or labels.dtype == torch.int): + self.config.problem_type = "single_label_classification" + else: + self.config.problem_type = "multi_label_classification" + + if self.config.problem_type == "regression": + loss_fct = MSELoss() + if self.num_labels == 1: + loss = loss_fct(logits.squeeze(), labels.squeeze()) + else: + loss = loss_fct(logits, labels) + elif self.config.problem_type == "single_label_classification": + loss_fct = CrossEntropyLoss() + loss = loss_fct(logits.view(-1, self.num_labels), labels.view(-1)) + elif self.config.problem_type == "multi_label_classification": + loss_fct = BCEWithLogitsLoss() + loss = loss_fct(logits, labels) + if not return_dict: + output = (logits,) + outputs[1:] + return ((loss,) + output) if loss is not None else output + + return SequenceClassifierOutput( + loss=loss, + logits=logits, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + ) + + +@auto_docstring +class RoFormerForMultipleChoice(RoFormerPreTrainedModel): + def __init__(self, config): + super().__init__(config) + + self.roformer = RoFormerModel(config) + self.sequence_summary = RoFormerSequenceSummary(config) + self.classifier = nn.Linear(config.hidden_size, 1) + + # Initialize weights and apply final processing + self.post_init() + + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.FloatTensor | None = None, + token_type_ids: torch.LongTensor | None = None, + inputs_embeds: torch.FloatTensor | None = None, + labels: torch.LongTensor | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + **kwargs, + ) -> MultipleChoiceModelOutput | tuple[torch.Tensor]: + r""" + input_ids (`torch.LongTensor` of shape `(batch_size, num_choices, sequence_length)`): + Indices of input sequence tokens in the vocabulary. + + Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and + [`PreTrainedTokenizer.__call__`] for details. + + [What are input IDs?](../glossary#input-ids) + token_type_ids (`torch.LongTensor` of shape `(batch_size, num_choices, sequence_length)`, *optional*): + Segment token indices to indicate first and second portions of the inputs. Indices are selected in `[0, + 1]`: + + - 0 corresponds to a *sentence A* token, + - 1 corresponds to a *sentence B* token. + + [What are token type IDs?](../glossary#token-type-ids) + inputs_embeds (`torch.FloatTensor` of shape `(batch_size, num_choices, sequence_length, hidden_size)`, *optional*): + Optionally, instead of passing `input_ids` you can choose to directly pass an embedded representation. This + is useful if you want more control over how to convert *input_ids* indices into associated vectors than the + model's internal embedding lookup matrix. + labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*): + Labels for computing the multiple choice classification loss. Indices should be in `[0, ..., + num_choices-1]` where `num_choices` is the size of the second dimension of the input tensors. (See + `input_ids` above) + """ + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + num_choices = input_ids.shape[1] if input_ids is not None else inputs_embeds.shape[1] + + input_ids = input_ids.view(-1, input_ids.size(-1)) if input_ids is not None else None + attention_mask = attention_mask.view(-1, attention_mask.size(-1)) if attention_mask is not None else None + token_type_ids = token_type_ids.view(-1, token_type_ids.size(-1)) if token_type_ids is not None else None + + inputs_embeds = ( + inputs_embeds.view(-1, inputs_embeds.size(-2), inputs_embeds.size(-1)) + if inputs_embeds is not None + else None + ) + + outputs = self.roformer( + input_ids, + attention_mask=attention_mask, + token_type_ids=token_type_ids, + inputs_embeds=inputs_embeds, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + + sequence_output = outputs[0] + + pooled_output = self.sequence_summary(sequence_output) + logits = self.classifier(pooled_output) + reshaped_logits = logits.view(-1, num_choices) + + loss = None + if labels is not None: + loss_fct = CrossEntropyLoss() + loss = loss_fct(reshaped_logits, labels) + + if not return_dict: + output = (reshaped_logits,) + outputs[1:] + return ((loss,) + output) if loss is not None else output + + return MultipleChoiceModelOutput( + loss=loss, + logits=reshaped_logits, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + ) + + +@auto_docstring +class RoFormerForTokenClassification(RoFormerPreTrainedModel): + def __init__(self, config): + super().__init__(config) + self.num_labels = config.num_labels + + self.roformer = RoFormerModel(config) + self.dropout = nn.Dropout(config.hidden_dropout_prob) + self.classifier = nn.Linear(config.hidden_size, config.num_labels) + + # Initialize weights and apply final processing + self.post_init() + + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.FloatTensor | None = None, + token_type_ids: torch.LongTensor | None = None, + inputs_embeds: torch.FloatTensor | None = None, + labels: torch.LongTensor | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + **kwargs, + ) -> TokenClassifierOutput | tuple[torch.Tensor]: + r""" + labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Labels for computing the token classification loss. Indices should be in `[0, ..., config.num_labels - 1]`. + """ + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + outputs = self.roformer( + input_ids, + attention_mask=attention_mask, + token_type_ids=token_type_ids, + inputs_embeds=inputs_embeds, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + + sequence_output = outputs[0] + + sequence_output = self.dropout(sequence_output) + logits = self.classifier(sequence_output) + + loss = None + if labels is not None: + loss_fct = CrossEntropyLoss() + loss = loss_fct(logits.view(-1, self.num_labels), labels.view(-1)) + + if not return_dict: + output = (logits,) + outputs[1:] + return ((loss,) + output) if loss is not None else output + + return TokenClassifierOutput( + loss=loss, + logits=logits, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + ) + + +@auto_docstring +class RoFormerForQuestionAnswering(RoFormerPreTrainedModel): + def __init__(self, config): + super().__init__(config) + + config.num_labels = 2 + self.num_labels = config.num_labels + + self.roformer = RoFormerModel(config) + self.qa_outputs = nn.Linear(config.hidden_size, config.num_labels) + + # Initialize weights and apply final processing + self.post_init() + + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.FloatTensor | None = None, + token_type_ids: torch.LongTensor | None = None, + inputs_embeds: torch.FloatTensor | None = None, + start_positions: torch.LongTensor | None = None, + end_positions: torch.LongTensor | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + **kwargs, + ) -> QuestionAnsweringModelOutput | tuple[torch.Tensor]: + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + outputs = self.roformer( + input_ids, + attention_mask=attention_mask, + token_type_ids=token_type_ids, + inputs_embeds=inputs_embeds, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + + sequence_output = outputs[0] + + logits = self.qa_outputs(sequence_output) + start_logits, end_logits = logits.split(1, dim=-1) + start_logits = start_logits.squeeze(-1) + end_logits = end_logits.squeeze(-1) + + total_loss = None + if start_positions is not None and end_positions is not None: + # If we are on multi-GPU, split add a dimension + if len(start_positions.size()) > 1: + start_positions = start_positions.squeeze(-1) + if len(end_positions.size()) > 1: + end_positions = end_positions.squeeze(-1) + # sometimes the start/end positions are outside our model inputs, we ignore these terms + ignored_index = start_logits.size(1) + start_positions = start_positions.clamp(0, ignored_index) + end_positions = end_positions.clamp(0, ignored_index) + + loss_fct = CrossEntropyLoss(ignore_index=ignored_index) + start_loss = loss_fct(start_logits, start_positions) + end_loss = loss_fct(end_logits, end_positions) + total_loss = (start_loss + end_loss) / 2 + + if not return_dict: + output = (start_logits, end_logits) + outputs[1:] + return ((total_loss,) + output) if total_loss is not None else output + + return QuestionAnsweringModelOutput( + loss=total_loss, + start_logits=start_logits, + end_logits=end_logits, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + ) + + +__all__ = [ + "RoFormerForCausalLM", + "RoFormerForMaskedLM", + "RoFormerForMultipleChoice", + "RoFormerForQuestionAnswering", + "RoFormerForSequenceClassification", + "RoFormerForTokenClassification", + "RoFormerLayer", + "RoFormerModel", + "RoFormerPreTrainedModel", +] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/roformer/tokenization_roformer.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/roformer/tokenization_roformer.py new file mode 100644 index 0000000000000000000000000000000000000000..fe50570b0499f3502033eb08e7099fb50fe413c1 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/roformer/tokenization_roformer.py @@ -0,0 +1,169 @@ +# Copyright 2021 The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""Tokenization class for RoFormer backed by 🤗 Tokenizers.""" + +from tokenizers import Tokenizer, decoders, models, normalizers, pre_tokenizers, processors +from tokenizers.pre_tokenizers import BertPreTokenizer, PreTokenizer + +from ...tokenization_utils_tokenizers import PreTrainedTokenizerFast +from ...utils import logging +from .tokenization_utils import JiebaPreTokenizer + + +logger = logging.get_logger(__name__) + +VOCAB_FILES_NAMES = {"vocab_file": "vocab.txt", "tokenizer_file": "tokenizer.json"} + + +class RoFormerTokenizer(PreTrainedTokenizerFast): + r""" + Construct a RoFormer tokenizer. Based on [Rust Jieba](https://pypi.org/project/rjieba/). + + This tokenizer inherits from [`PreTrainedTokenizerFast`] which contains most of the main methods. Users should + refer to this superclass for more information regarding those methods. + + Example: + + ```python + >>> from transformers import RoFormerTokenizer + + >>> tokenizer = RoFormerTokenizer.from_pretrained("junnyu/roformer_chinese_base") + >>> tokenizer.tokenize("今天天气非常好。") + ['今', '天', '天', '气', '非常', '好', '。'] + ``` + """ + + vocab_files_names = VOCAB_FILES_NAMES + + def __init__( + self, + vocab: dict[str, int] | None = None, + do_lower_case=True, + unk_token="[UNK]", + sep_token="[SEP]", + pad_token="[PAD]", + cls_token="[CLS]", + mask_token="[MASK]", + tokenize_chinese_chars=True, + strip_accents=None, + **kwargs, + ): + tokenizer = Tokenizer(models.WordPiece(vocab, unk_token=str(unk_token))) + tokenizer.normalizer = normalizers.BertNormalizer( + clean_text=True, + handle_chinese_chars=False, + strip_accents=strip_accents, + lowercase=do_lower_case, + ) + tokenizer.pre_tokenizer = pre_tokenizers.PreTokenizer.custom(JiebaPreTokenizer(vocab)) + + tokenizer.decoder = decoders.WordPiece(prefix="##") + self._tokenizer = tokenizer + super().__init__( + do_lower_case=do_lower_case, + unk_token=unk_token, + sep_token=sep_token, + pad_token=pad_token, + cls_token=cls_token, + mask_token=mask_token, + tokenize_chinese_chars=tokenize_chinese_chars, + strip_accents=strip_accents, + **kwargs, + ) + cls_ = str(cls_token) + sep_ = str(sep_token) + self._tokenizer.post_processor = processors.TemplateProcessing( + single=f"{cls_}:0 $A:0 {sep_}:0", + pair=f"{cls_}:0 $A:0 {sep_}:0 $B:1 {sep_}:1", + special_tokens=[ + (cls_, self.cls_token_id), + (sep_, self.sep_token_id), + ], + ) + + def __getstate__(self): + state = self.__dict__.copy() + tokenizer_copy = Tokenizer.from_str(state["_tokenizer"].to_str()) + tokenizer_copy.pre_tokenizer = BertPreTokenizer() + state["_tokenizer"] = tokenizer_copy + return state + + def __setstate__(self, d): + self.__dict__ = d + vocab = self.__dict__["_tokenizer"].get_vocab() + self.__dict__["_tokenizer"].pre_tokenizer = PreTokenizer.custom(JiebaPreTokenizer(vocab)) + + def build_inputs_with_special_tokens(self, token_ids_0, token_ids_1=None): + """ + Build model inputs from a sequence or a pair of sequence for sequence classification tasks by concatenating and + adding special tokens. A RoFormer sequence has the following format: + + - single sequence: `[CLS] X [SEP]` + - pair of sequences: `[CLS] A [SEP] B [SEP]` + + Args: + token_ids_0 (`List[int]`): + List of IDs to which the special tokens will be added. + token_ids_1 (`List[int]`, *optional*): + Optional second list of IDs for sequence pairs. + + Returns: + `List[int]`: List of [input IDs](../glossary#input-ids) with the appropriate special tokens. + """ + output = [self.cls_token_id] + token_ids_0 + [self.sep_token_id] + + if token_ids_1 is not None: + output += token_ids_1 + [self.sep_token_id] + + return output + + def create_token_type_ids_from_sequences( + self, token_ids_0: list[int], token_ids_1: list[int] | None = None + ) -> list[int]: + """ + Create token type IDs for RoFormer sequence pairs. + + The first sequence and associated special tokens are mapped to 0, while the second sequence (if provided) and + its trailing separator are mapped to 1. + """ + sep = [self.sep_token_id] + cls = [self.cls_token_id] + + if token_ids_1 is None: + return len(cls + token_ids_0 + sep) * [0] + + return len(cls + token_ids_0 + sep) * [0] + len(token_ids_1 + sep) * [1] + + def save_vocabulary(self, save_directory: str, filename_prefix: str | None = None) -> tuple[str]: + files = self._tokenizer.model.save(save_directory, name=filename_prefix) + return tuple(files) + + def save_pretrained( + self, + save_directory, + legacy_format=None, + filename_prefix=None, + push_to_hub=False, + **kwargs, + ): + self.backend_tokenizer.pre_tokenizer = BertPreTokenizer() + result = super().save_pretrained(save_directory, legacy_format, filename_prefix, push_to_hub, **kwargs) + vocab = self.backend_tokenizer.get_vocab() + self.backend_tokenizer.pre_tokenizer = PreTokenizer.custom(JiebaPreTokenizer(vocab)) + return result + + +RoFormerTokenizerFast = RoFormerTokenizer + +__all__ = ["RoFormerTokenizer", "RoFormerTokenizerFast"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/roformer/tokenization_utils.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/roformer/tokenization_utils.py new file mode 100644 index 0000000000000000000000000000000000000000..af1686911e500e4ebae8855a08059c5c179ba424 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/roformer/tokenization_utils.py @@ -0,0 +1,65 @@ +# Copyright 2021 The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""Tokenization utils for RoFormer.""" + +from tokenizers import NormalizedString, PreTokenizedString, normalizers + + +class JiebaPreTokenizer: + def __init__(self, vocab) -> None: + self.vocab = vocab + self.normalizers = normalizers.BertNormalizer( + clean_text=False, + handle_chinese_chars=True, + strip_accents=False, + lowercase=False, + ) + try: + import rjieba + except ImportError: + raise ImportError( + "You need to install rjieba to use RoFormerTokenizer. " + "See https://pypi.org/project/rjieba/ for installation." + ) + self.jieba = rjieba + + def jieba_split(self, i: int, normalized_string: NormalizedString) -> list[NormalizedString]: + splits = [] + + # this code slice normalized_string is too slow (6s) but test_alignment_methods can pass + for token, start, end in self.jieba.tokenize(str(normalized_string), hmm=False): + if token in self.vocab: + splits.append(normalized_string[start:end]) + else: + token_list = self.normalizers.normalize_str(token).split() + for token in token_list: + if token: + end = start + len(token) + splits.append(normalized_string[start:end]) + start = end + + # this code test_alignment_methods can't pass but fast (300ms) + # for token in self.jieba.cut(str(normalized_string), False): + # if token in self.vocab: + # splits.append(NormalizedString(token)) + # else: + # token_list = self.normalizers.normalize_str(token).split() + # for token in token_list: + # if token: + # splits.append(NormalizedString(token)) + + return splits + + def pre_tokenize(self, pretok: PreTokenizedString): + pretok.split(self.jieba_split) diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/rt_detr/__init__.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/rt_detr/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..cd1fac5b679dc5ca527dcc0a6a45b9a873daa3dc --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/rt_detr/__init__.py @@ -0,0 +1,33 @@ +# Copyright 2024 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + + +from typing import TYPE_CHECKING + +from ...utils import _LazyModule +from ...utils.import_utils import define_import_structure + + +if TYPE_CHECKING: + from .configuration_rt_detr import * + from .configuration_rt_detr_resnet import * + from .image_processing_rt_detr import * + from .image_processing_rt_detr_fast import * + from .modeling_rt_detr import * + from .modeling_rt_detr_resnet import * +else: + import sys + + _file = globals()["__file__"] + sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__) diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/rt_detr/configuration_rt_detr.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/rt_detr/configuration_rt_detr.py new file mode 100644 index 0000000000000000000000000000000000000000..ff1f1fd131167f1ec58eda7b3d8af718c89430b7 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/rt_detr/configuration_rt_detr.py @@ -0,0 +1,298 @@ +# Copyright 2024 The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""RT-DETR model configuration""" + +from ...backbone_utils import consolidate_backbone_kwargs_to_config +from ...configuration_utils import PreTrainedConfig +from ...utils import logging +from ..auto import AutoConfig + + +logger = logging.get_logger(__name__) + + +class RTDetrConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`RTDetrModel`]. It is used to instantiate a + RT-DETR model according to the specified arguments, defining the model architecture. Instantiating a configuration + with the defaults will yield a similar configuration to that of the RT-DETR + [PekingU/rtdetr_r50vd](https://huggingface.co/PekingU/rtdetr_r50vd) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + initializer_range (`float`, *optional*, defaults to 0.01): + The standard deviation of the truncated_normal_initializer for initializing all weight matrices. + initializer_bias_prior_prob (`float`, *optional*): + The prior probability used by the bias initializer to initialize biases for `enc_score_head` and `class_embed`. + If `None`, `prior_prob` computed as `prior_prob = 1 / (num_labels + 1)` while initializing model weights. + layer_norm_eps (`float`, *optional*, defaults to 1e-05): + The epsilon used by the layer normalization layers. + batch_norm_eps (`float`, *optional*, defaults to 1e-05): + The epsilon used by the batch normalization layers. + backbone_config (`Union[dict, "PreTrainedConfig"]`, *optional*, defaults to `RTDetrResNetConfig()`): + The configuration of the backbone model. + freeze_backbone_batch_norms (`bool`, *optional*, defaults to `True`): + Whether to freeze the batch normalization layers in the backbone. + encoder_hidden_dim (`int`, *optional*, defaults to 256): + Dimension of the layers in hybrid encoder. + encoder_in_channels (`list`, *optional*, defaults to `[512, 1024, 2048]`): + Multi level features input for encoder. + feat_strides (`list[int]`, *optional*, defaults to `[8, 16, 32]`): + Strides used in each feature map. + encoder_layers (`int`, *optional*, defaults to 1): + Total of layers to be used by the encoder. + encoder_ffn_dim (`int`, *optional*, defaults to 1024): + Dimension of the "intermediate" (often named feed-forward) layer in decoder. + encoder_attention_heads (`int`, *optional*, defaults to 8): + Number of attention heads for each attention layer in the Transformer encoder. + dropout (`float`, *optional*, defaults to 0.0): + The ratio for all dropout layers. + activation_dropout (`float`, *optional*, defaults to 0.0): + The dropout ratio for activations inside the fully connected layer. + encode_proj_layers (`list[int]`, *optional*, defaults to `[2]`): + Indexes of the projected layers to be used in the encoder. + positional_encoding_temperature (`int`, *optional*, defaults to 10000): + The temperature parameter used to create the positional encodings. + encoder_activation_function (`str`, *optional*, defaults to `"gelu"`): + The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`, + `"relu"`, `"silu"` and `"gelu_new"` are supported. + activation_function (`str`, *optional*, defaults to `"silu"`): + The non-linear activation function (function or string) in the general layer. If string, `"gelu"`, + `"relu"`, `"silu"` and `"gelu_new"` are supported. + eval_size (`tuple[int, int]`, *optional*): + Height and width used to computes the effective height and width of the position embeddings after taking + into account the stride. + normalize_before (`bool`, *optional*, defaults to `False`): + Determine whether to apply layer normalization in the transformer encoder layer before self-attention and + feed-forward modules. + hidden_expansion (`float`, *optional*, defaults to 1.0): + Expansion ratio to enlarge the dimension size of RepVGGBlock and CSPRepLayer. + d_model (`int`, *optional*, defaults to 256): + Dimension of the layers exclude hybrid encoder. + num_queries (`int`, *optional*, defaults to 300): + Number of object queries. + decoder_in_channels (`list`, *optional*, defaults to `[256, 256, 256]`): + Multi level features dimension for decoder + decoder_ffn_dim (`int`, *optional*, defaults to 1024): + Dimension of the "intermediate" (often named feed-forward) layer in decoder. + num_feature_levels (`int`, *optional*, defaults to 3): + The number of input feature levels. + decoder_n_points (`int`, *optional*, defaults to 4): + The number of sampled keys in each feature level for each attention head in the decoder. + decoder_layers (`int`, *optional*, defaults to 6): + Number of decoder layers. + decoder_attention_heads (`int`, *optional*, defaults to 8): + Number of attention heads for each attention layer in the Transformer decoder. + decoder_activation_function (`str`, *optional*, defaults to `"relu"`): + The non-linear activation function (function or string) in the decoder. If string, `"gelu"`, + `"relu"`, `"silu"` and `"gelu_new"` are supported. + attention_dropout (`float`, *optional*, defaults to 0.0): + The dropout ratio for the attention probabilities. + num_denoising (`int`, *optional*, defaults to 100): + The total number of denoising tasks or queries to be used for contrastive denoising. + label_noise_ratio (`float`, *optional*, defaults to 0.5): + The fraction of denoising labels to which random noise should be added. + box_noise_scale (`float`, *optional*, defaults to 1.0): + Scale or magnitude of noise to be added to the bounding boxes. + learn_initial_query (`bool`, *optional*, defaults to `False`): + Indicates whether the initial query embeddings for the decoder should be learned during training + anchor_image_size (`tuple[int, int]`, *optional*): + Height and width of the input image used during evaluation to generate the bounding box anchors. If None, automatic generate anchor is applied. + disable_custom_kernels (`bool`, *optional*, defaults to `True`): + Whether to disable custom kernels. + with_box_refine (`bool`, *optional*, defaults to `True`): + Whether to apply iterative bounding box refinement, where each decoder layer refines the bounding boxes + based on the predictions from the previous layer. + is_encoder_decoder (`bool`, *optional*, defaults to `True`): + Whether the architecture has an encoder decoder structure. + matcher_alpha (`float`, *optional*, defaults to 0.25): + Parameter alpha used by the Hungarian Matcher. + matcher_gamma (`float`, *optional*, defaults to 2.0): + Parameter gamma used by the Hungarian Matcher. + matcher_class_cost (`float`, *optional*, defaults to 2.0): + The relative weight of the class loss used by the Hungarian Matcher. + matcher_bbox_cost (`float`, *optional*, defaults to 5.0): + The relative weight of the bounding box loss used by the Hungarian Matcher. + matcher_giou_cost (`float`, *optional*, defaults to 2.0): + The relative weight of the giou loss of used by the Hungarian Matcher. + use_focal_loss (`bool`, *optional*, defaults to `True`): + Parameter informing if focal focal should be used. + auxiliary_loss (`bool`, *optional*, defaults to `True`): + Whether auxiliary decoding losses (loss at each decoder layer) are to be used. + focal_loss_alpha (`float`, *optional*, defaults to 0.75): + Parameter alpha used to compute the focal loss. + focal_loss_gamma (`float`, *optional*, defaults to 2.0): + Parameter gamma used to compute the focal loss. + weight_loss_vfl (`float`, *optional*, defaults to 1.0): + Relative weight of the varifocal loss in the object detection loss. + weight_loss_bbox (`float`, *optional*, defaults to 5.0): + Relative weight of the L1 bounding box loss in the object detection loss. + weight_loss_giou (`float`, *optional*, defaults to 2.0): + Relative weight of the generalized IoU loss in the object detection loss. + eos_coefficient (`float`, *optional*, defaults to 0.0001): + Relative classification weight of the 'no-object' class in the object detection loss. + + Examples: + + ```python + >>> from transformers import RTDetrConfig, RTDetrModel + + >>> # Initializing a RT-DETR configuration + >>> configuration = RTDetrConfig() + + >>> # Initializing a model (with random weights) from the configuration + >>> model = RTDetrModel(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "rt_detr" + sub_configs = {"backbone_config": AutoConfig} + layer_types = ["basic", "bottleneck"] + attribute_map = { + "hidden_size": "d_model", + "num_attention_heads": "encoder_attention_heads", + } + + def __init__( + self, + initializer_range=0.01, + initializer_bias_prior_prob=None, + layer_norm_eps=1e-5, + batch_norm_eps=1e-5, + # backbone + backbone_config=None, + freeze_backbone_batch_norms=True, + # encoder HybridEncoder + encoder_hidden_dim=256, + encoder_in_channels=[512, 1024, 2048], + feat_strides=[8, 16, 32], + encoder_layers=1, + encoder_ffn_dim=1024, + encoder_attention_heads=8, + dropout=0.0, + activation_dropout=0.0, + encode_proj_layers=[2], + positional_encoding_temperature=10000, + encoder_activation_function="gelu", + activation_function="silu", + eval_size=None, + normalize_before=False, + hidden_expansion=1.0, + # decoder RTDetrTransformer + d_model=256, + num_queries=300, + decoder_in_channels=[256, 256, 256], + decoder_ffn_dim=1024, + num_feature_levels=3, + decoder_n_points=4, + decoder_layers=6, + decoder_attention_heads=8, + decoder_activation_function="relu", + attention_dropout=0.0, + num_denoising=100, + label_noise_ratio=0.5, + box_noise_scale=1.0, + learn_initial_query=False, + anchor_image_size=None, + disable_custom_kernels=True, + with_box_refine=True, + is_encoder_decoder=True, + # Loss + matcher_alpha=0.25, + matcher_gamma=2.0, + matcher_class_cost=2.0, + matcher_bbox_cost=5.0, + matcher_giou_cost=2.0, + use_focal_loss=True, + auxiliary_loss=True, + focal_loss_alpha=0.75, + focal_loss_gamma=2.0, + weight_loss_vfl=1.0, + weight_loss_bbox=5.0, + weight_loss_giou=2.0, + eos_coefficient=1e-4, + **kwargs, + ): + self.initializer_range = initializer_range + self.initializer_bias_prior_prob = initializer_bias_prior_prob + self.layer_norm_eps = layer_norm_eps + self.batch_norm_eps = batch_norm_eps + + backbone_config, kwargs = consolidate_backbone_kwargs_to_config( + backbone_config=backbone_config, + default_config_type="rt_detr_resnet", + default_config_kwargs={ + "out_indices": [2, 3, 4], + }, + **kwargs, + ) + + self.backbone_config = backbone_config + self.freeze_backbone_batch_norms = freeze_backbone_batch_norms + # encoder + self.encoder_hidden_dim = encoder_hidden_dim + self.encoder_in_channels = encoder_in_channels + self.feat_strides = feat_strides + self.encoder_attention_heads = encoder_attention_heads + self.encoder_ffn_dim = encoder_ffn_dim + self.dropout = dropout + self.activation_dropout = activation_dropout + self.encode_proj_layers = encode_proj_layers + self.encoder_layers = encoder_layers + self.positional_encoding_temperature = positional_encoding_temperature + self.eval_size = eval_size + self.normalize_before = normalize_before + self.encoder_activation_function = encoder_activation_function + self.activation_function = activation_function + self.hidden_expansion = hidden_expansion + # decoder + self.d_model = d_model + self.num_queries = num_queries + self.decoder_ffn_dim = decoder_ffn_dim + self.decoder_in_channels = decoder_in_channels + self.num_feature_levels = num_feature_levels + self.decoder_n_points = decoder_n_points + self.decoder_layers = decoder_layers + self.decoder_attention_heads = decoder_attention_heads + self.decoder_activation_function = decoder_activation_function + self.attention_dropout = attention_dropout + self.num_denoising = num_denoising + self.label_noise_ratio = label_noise_ratio + self.box_noise_scale = box_noise_scale + self.learn_initial_query = learn_initial_query + self.anchor_image_size = anchor_image_size + self.auxiliary_loss = auxiliary_loss + self.disable_custom_kernels = disable_custom_kernels + self.with_box_refine = with_box_refine + # Loss + self.matcher_alpha = matcher_alpha + self.matcher_gamma = matcher_gamma + self.matcher_class_cost = matcher_class_cost + self.matcher_bbox_cost = matcher_bbox_cost + self.matcher_giou_cost = matcher_giou_cost + self.use_focal_loss = use_focal_loss + self.focal_loss_alpha = focal_loss_alpha + self.focal_loss_gamma = focal_loss_gamma + self.weight_loss_vfl = weight_loss_vfl + self.weight_loss_bbox = weight_loss_bbox + self.weight_loss_giou = weight_loss_giou + self.eos_coefficient = eos_coefficient + super().__init__(is_encoder_decoder=is_encoder_decoder, **kwargs) + + +__all__ = ["RTDetrConfig"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/rt_detr/configuration_rt_detr_resnet.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/rt_detr/configuration_rt_detr_resnet.py new file mode 100644 index 0000000000000000000000000000000000000000..d647dde8c3acf21fa55fef5bbb4f144d682ea0fa --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/rt_detr/configuration_rt_detr_resnet.py @@ -0,0 +1,111 @@ +# Copyright 2024 The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""RT-DETR ResNet model configuration""" + +from ...backbone_utils import BackboneConfigMixin +from ...configuration_utils import PreTrainedConfig +from ...utils import logging + + +logger = logging.get_logger(__name__) + + +class RTDetrResNetConfig(BackboneConfigMixin, PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`RTDetrResnetBackbone`]. It is used to instantiate an + ResNet model according to the specified arguments, defining the model architecture. Instantiating a configuration + with the defaults will yield a similar configuration to that of the ResNet + [microsoft/resnet-50](https://huggingface.co/microsoft/resnet-50) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + num_channels (`int`, *optional*, defaults to 3): + The number of input channels. + embedding_size (`int`, *optional*, defaults to 64): + Dimensionality (hidden size) for the embedding layer. + hidden_sizes (`list[int]`, *optional*, defaults to `[256, 512, 1024, 2048]`): + Dimensionality (hidden size) at each stage. + depths (`list[int]`, *optional*, defaults to `[3, 4, 6, 3]`): + Depth (number of layers) for each stage. + layer_type (`str`, *optional*, defaults to `"bottleneck"`): + The layer to use, it can be either `"basic"` (used for smaller models, like resnet-18 or resnet-34) or + `"bottleneck"` (used for larger models like resnet-50 and above). + hidden_act (`str`, *optional*, defaults to `"relu"`): + The non-linear activation function in each block. If string, `"gelu"`, `"relu"`, `"selu"` and `"gelu_new"` + are supported. + downsample_in_first_stage (`bool`, *optional*, defaults to `False`): + If `True`, the first stage will downsample the inputs using a `stride` of 2. + downsample_in_bottleneck (`bool`, *optional*, defaults to `False`): + If `True`, the first conv 1x1 in ResNetBottleNeckLayer will downsample the inputs using a `stride` of 2. + out_features (`list[str]`, *optional*): + If used as backbone, list of features to output. Can be any of `"stem"`, `"stage1"`, `"stage2"`, etc. + (depending on how many stages the model has). If unset and `out_indices` is set, will default to the + corresponding stages. If unset and `out_indices` is unset, will default to the last stage. Must be in the + same order as defined in the `stage_names` attribute. + out_indices (`list[int]`, *optional*): + If used as backbone, list of indices of features to output. Can be any of 0, 1, 2, etc. (depending on how + many stages the model has). If unset and `out_features` is set, will default to the corresponding stages. + If unset and `out_features` is unset, will default to the last stage. Must be in the + same order as defined in the `stage_names` attribute. + + Example: + ```python + >>> from transformers import RTDetrResNetConfig, RTDetrResnetBackbone + + >>> # Initializing a ResNet resnet-50 style configuration + >>> configuration = RTDetrResNetConfig() + + >>> # Initializing a model (with random weights) from the resnet-50 style configuration + >>> model = RTDetrResnetBackbone(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ``` + """ + + model_type = "rt_detr_resnet" + layer_types = ["basic", "bottleneck"] + + def __init__( + self, + num_channels=3, + embedding_size=64, + hidden_sizes=[256, 512, 1024, 2048], + depths=[3, 4, 6, 3], + layer_type="bottleneck", + hidden_act="relu", + downsample_in_first_stage=False, + downsample_in_bottleneck=False, + out_features=None, + out_indices=None, + **kwargs, + ): + super().__init__(**kwargs) + if layer_type not in self.layer_types: + raise ValueError(f"layer_type={layer_type} is not one of {','.join(self.layer_types)}") + self.num_channels = num_channels + self.embedding_size = embedding_size + self.hidden_sizes = hidden_sizes + self.depths = depths + self.layer_type = layer_type + self.hidden_act = hidden_act + self.downsample_in_first_stage = downsample_in_first_stage + self.downsample_in_bottleneck = downsample_in_bottleneck + self.stage_names = ["stem"] + [f"stage{idx}" for idx in range(1, len(depths) + 1)] + self.set_output_features_output_indices(out_indices=out_indices, out_features=out_features) + + +__all__ = ["RTDetrResNetConfig"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/rt_detr/image_processing_rt_detr.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/rt_detr/image_processing_rt_detr.py new file mode 100644 index 0000000000000000000000000000000000000000..972e589a9c14a7d4839615cc677b77add2853abc --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/rt_detr/image_processing_rt_detr.py @@ -0,0 +1,1041 @@ +# Copyright 2024 The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""Image processor class for RT-DETR.""" + +import pathlib +from collections.abc import Iterable +from typing import Any + +import numpy as np + +from ...feature_extraction_utils import BatchFeature +from ...image_processing_utils import BaseImageProcessor, get_size_dict +from ...image_transforms import ( + PaddingMode, + center_to_corners_format, + corners_to_center_format, + get_size_with_aspect_ratio, + pad, + rescale, + resize, + to_channel_dimension_format, +) +from ...image_utils import ( + IMAGENET_DEFAULT_MEAN, + IMAGENET_DEFAULT_STD, + AnnotationFormat, + AnnotationType, + ChannelDimension, + ImageInput, + PILImageResampling, + get_image_size, + infer_channel_dimension_format, + is_scaled_image, + make_flat_list_of_images, + to_numpy_array, + valid_images, + validate_annotations, + validate_preprocess_arguments, +) +from ...processing_utils import ImagesKwargs +from ...utils import ( + filter_out_non_signature_kwargs, + is_torch_available, + logging, + requires_backends, +) +from ...utils.generic import TensorType + + +if is_torch_available(): + import torch + + +logger = logging.get_logger(__name__) # pylint: disable=invalid-name + +SUPPORTED_ANNOTATION_FORMATS = (AnnotationFormat.COCO_DETECTION,) + + +class RTDetrImageProcessorKwargs(ImagesKwargs, total=False): + r""" + format (`str`, *optional*, defaults to `AnnotationFormat.COCO_DETECTION`): + Data format of the annotations. One of "coco_detection" or "coco_panoptic". + do_convert_annotations (`bool`, *optional*, defaults to `True`): + Controls whether to convert the annotations to the format expected by the RT_DETR model. Converts the + bounding boxes to the format `(center_x, center_y, width, height)` and in the range `[0, 1]`. + Can be overridden by the `do_convert_annotations` parameter in the `preprocess` method. + return_segmentation_masks (`bool`, *optional*, defaults to `False`): + Whether to return segmentation masks. + annotations (`AnnotationType` or `list[AnnotationType]`, *optional*): + Annotations to transform according to the padding that is applied to the images. + masks_path (`str` or `pathlib.Path`, *optional*): + Path to the directory containing the segmentation masks. + """ + + format: str | AnnotationFormat + do_convert_annotations: bool + return_segmentation_masks: bool + annotations: AnnotationType | list[AnnotationType] | None + masks_path: str | pathlib.Path | None + + +def get_resize_output_image_size( + input_image: np.ndarray, + size: int | tuple[int, int] | list[int], + max_size: int | None = None, + input_data_format: str | ChannelDimension | None = None, +) -> tuple[int, int]: + """ + Computes the output image size given the input image size and the desired output size. If the desired output size + is a tuple or list, the output image size is returned as is. If the desired output size is an integer, the output + image size is computed by keeping the aspect ratio of the input image size. + + Args: + input_image (`np.ndarray`): + The image to resize. + size (`int` or `tuple[int, int]` or `list[int]`): + The desired output size. + max_size (`int`, *optional*): + The maximum allowed output size. + input_data_format (`ChannelDimension` or `str`, *optional*): + The channel dimension format of the input image. If not provided, it will be inferred from the input image. + """ + image_size = get_image_size(input_image, input_data_format) + if isinstance(size, (list, tuple)): + return size + + return get_size_with_aspect_ratio(image_size, size, max_size) + + +# Copied from transformers.models.detr.image_processing_detr.get_image_size_for_max_height_width +def get_image_size_for_max_height_width( + input_image: np.ndarray, + max_height: int, + max_width: int, + input_data_format: str | ChannelDimension | None = None, +) -> tuple[int, int]: + """ + Computes the output image size given the input image and the maximum allowed height and width. Keep aspect ratio. + Important, even if image_height < max_height and image_width < max_width, the image will be resized + to at least one of the edges be equal to max_height or max_width. + For example: + - input_size: (100, 200), max_height: 50, max_width: 50 -> output_size: (25, 50) + - input_size: (100, 200), max_height: 200, max_width: 500 -> output_size: (200, 400) + Args: + input_image (`np.ndarray`): + The image to resize. + max_height (`int`): + The maximum allowed height. + max_width (`int`): + The maximum allowed width. + input_data_format (`ChannelDimension` or `str`, *optional*): + The channel dimension format of the input image. If not provided, it will be inferred from the input image. + """ + image_size = get_image_size(input_image, input_data_format) + height, width = image_size + height_scale = max_height / height + width_scale = max_width / width + min_scale = min(height_scale, width_scale) + new_height = int(height * min_scale) + new_width = int(width * min_scale) + return new_height, new_width + + +# Copied from transformers.models.detr.image_processing_detr.safe_squeeze +def safe_squeeze(arr: np.ndarray, axis: int | None = None) -> np.ndarray: + """ + Squeezes an array, but only if the axis specified has dim 1. + """ + if axis is None: + return arr.squeeze() + + try: + return arr.squeeze(axis=axis) + except ValueError: + return arr + + +# Copied from transformers.models.detr.image_processing_detr.normalize_annotation +def normalize_annotation(annotation: dict, image_size: tuple[int, int]) -> dict: + image_height, image_width = image_size + norm_annotation = {} + for key, value in annotation.items(): + if key == "boxes": + boxes = value + boxes = corners_to_center_format(boxes) + boxes /= np.asarray([image_width, image_height, image_width, image_height], dtype=np.float32) + norm_annotation[key] = boxes + else: + norm_annotation[key] = value + return norm_annotation + + +# Copied from transformers.models.detr.image_processing_detr.max_across_indices +def max_across_indices(values: Iterable[Any]) -> list[Any]: + """ + Return the maximum value across all indices of an iterable of values. + """ + return [max(values_i) for values_i in zip(*values)] + + +# Copied from transformers.models.detr.image_processing_detr.get_max_height_width +def get_max_height_width( + images: list[np.ndarray], input_data_format: str | ChannelDimension | None = None +) -> list[int]: + """ + Get the maximum height and width across all images in a batch. + """ + if input_data_format is None: + input_data_format = infer_channel_dimension_format(images[0]) + + if input_data_format == ChannelDimension.FIRST: + _, max_height, max_width = max_across_indices([img.shape for img in images]) + elif input_data_format == ChannelDimension.LAST: + max_height, max_width, _ = max_across_indices([img.shape for img in images]) + else: + raise ValueError(f"Invalid channel dimension format: {input_data_format}") + return (max_height, max_width) + + +# Copied from transformers.models.detr.image_processing_detr.make_pixel_mask +def make_pixel_mask( + image: np.ndarray, output_size: tuple[int, int], input_data_format: str | ChannelDimension | None = None +) -> np.ndarray: + """ + Make a pixel mask for the image, where 1 indicates a valid pixel and 0 indicates padding. + + Args: + image (`np.ndarray`): + Image to make the pixel mask for. + output_size (`tuple[int, int]`): + Output size of the mask. + """ + input_height, input_width = get_image_size(image, channel_dim=input_data_format) + mask = np.zeros(output_size, dtype=np.int64) + mask[:input_height, :input_width] = 1 + return mask + + +def prepare_coco_detection_annotation( + image, + target, + return_segmentation_masks: bool = False, + input_data_format: ChannelDimension | str | None = None, +): + """ + Convert the target in COCO format into the format expected by RTDETR. + """ + image_height, image_width = get_image_size(image, channel_dim=input_data_format) + + image_id = target["image_id"] + image_id = np.asarray([image_id], dtype=np.int64) + + # Get all COCO annotations for the given image. + annotations = target["annotations"] + annotations = [obj for obj in annotations if "iscrowd" not in obj or obj["iscrowd"] == 0] + + classes = [obj["category_id"] for obj in annotations] + classes = np.asarray(classes, dtype=np.int64) + + # for conversion to coco api + area = np.asarray([obj["area"] for obj in annotations], dtype=np.float32) + iscrowd = np.asarray([obj.get("iscrowd", 0) for obj in annotations], dtype=np.int64) + + boxes = [obj["bbox"] for obj in annotations] + # guard against no boxes via resizing + boxes = np.asarray(boxes, dtype=np.float32).reshape(-1, 4) + boxes[:, 2:] += boxes[:, :2] + boxes[:, 0::2] = boxes[:, 0::2].clip(min=0, max=image_width) + boxes[:, 1::2] = boxes[:, 1::2].clip(min=0, max=image_height) + + keep = (boxes[:, 3] > boxes[:, 1]) & (boxes[:, 2] > boxes[:, 0]) + + new_target = {} + new_target["image_id"] = image_id + new_target["class_labels"] = classes[keep] + new_target["boxes"] = boxes[keep] + new_target["area"] = area[keep] + new_target["iscrowd"] = iscrowd[keep] + new_target["orig_size"] = np.asarray([int(image_height), int(image_width)], dtype=np.int64) + + if annotations and "keypoints" in annotations[0]: + keypoints = [obj["keypoints"] for obj in annotations] + # Converting the filtered keypoints list to a numpy array + keypoints = np.asarray(keypoints, dtype=np.float32) + # Apply the keep mask here to filter the relevant annotations + keypoints = keypoints[keep] + num_keypoints = keypoints.shape[0] + keypoints = keypoints.reshape((-1, 3)) if num_keypoints else keypoints + new_target["keypoints"] = keypoints + + return new_target + + +# Copied from transformers.models.detr.image_processing_detr.resize_annotation +def resize_annotation( + annotation: dict[str, Any], + orig_size: tuple[int, int], + target_size: tuple[int, int], + threshold: float = 0.5, + resample: PILImageResampling = PILImageResampling.NEAREST, +): + """ + Resizes an annotation to a target size. + + Args: + annotation (`dict[str, Any]`): + The annotation dictionary. + orig_size (`tuple[int, int]`): + The original size of the input image. + target_size (`tuple[int, int]`): + The target size of the image, as returned by the preprocessing `resize` step. + threshold (`float`, *optional*, defaults to 0.5): + The threshold used to binarize the segmentation masks. + resample (`PILImageResampling`, defaults to `PILImageResampling.NEAREST`): + The resampling filter to use when resizing the masks. + """ + ratios = tuple(float(s) / float(s_orig) for s, s_orig in zip(target_size, orig_size)) + ratio_height, ratio_width = ratios + + new_annotation = {} + new_annotation["size"] = target_size + + for key, value in annotation.items(): + if key == "boxes": + boxes = value + scaled_boxes = boxes * np.asarray([ratio_width, ratio_height, ratio_width, ratio_height], dtype=np.float32) + new_annotation["boxes"] = scaled_boxes + elif key == "area": + area = value + scaled_area = area * (ratio_width * ratio_height) + new_annotation["area"] = scaled_area + elif key == "masks": + masks = value[:, None] + masks = np.array([resize(mask, target_size, resample=resample) for mask in masks]) + masks = masks.astype(np.float32) + masks = masks[:, 0] > threshold + new_annotation["masks"] = masks + elif key == "size": + new_annotation["size"] = target_size + else: + new_annotation[key] = value + + return new_annotation + + +class RTDetrImageProcessor(BaseImageProcessor): + r""" + Constructs a RT-DETR image processor. + + Args: + format (`str`, *optional*, defaults to `AnnotationFormat.COCO_DETECTION`): + Data format of the annotations. One of "coco_detection" or "coco_panoptic". + do_resize (`bool`, *optional*, defaults to `True`): + Controls whether to resize the image's (height, width) dimensions to the specified `size`. Can be + overridden by the `do_resize` parameter in the `preprocess` method. + size (`dict[str, int]` *optional*, defaults to `{"height": 640, "width": 640}`): + Size of the image's `(height, width)` dimensions after resizing. Can be overridden by the `size` parameter + in the `preprocess` method. Available options are: + - `{"height": int, "width": int}`: The image will be resized to the exact size `(height, width)`. + Do NOT keep the aspect ratio. + - `{"shortest_edge": int, "longest_edge": int}`: The image will be resized to a maximum size respecting + the aspect ratio and keeping the shortest edge less or equal to `shortest_edge` and the longest edge + less or equal to `longest_edge`. + - `{"max_height": int, "max_width": int}`: The image will be resized to the maximum size respecting the + aspect ratio and keeping the height less or equal to `max_height` and the width less or equal to + `max_width`. + resample (`PILImageResampling`, *optional*, defaults to `PILImageResampling.BILINEAR`): + Resampling filter to use if resizing the image. + do_rescale (`bool`, *optional*, defaults to `True`): + Controls whether to rescale the image by the specified scale `rescale_factor`. Can be overridden by the + `do_rescale` parameter in the `preprocess` method. + rescale_factor (`int` or `float`, *optional*, defaults to `1/255`): + Scale factor to use if rescaling the image. Can be overridden by the `rescale_factor` parameter in the + `preprocess` method. + Controls whether to normalize the image. Can be overridden by the `do_normalize` parameter in the + `preprocess` method. + do_normalize (`bool`, *optional*, defaults to `False`): + Whether to normalize the image. + image_mean (`float` or `list[float]`, *optional*, defaults to `IMAGENET_DEFAULT_MEAN`): + Mean values to use when normalizing the image. Can be a single value or a list of values, one for each + channel. Can be overridden by the `image_mean` parameter in the `preprocess` method. + image_std (`float` or `list[float]`, *optional*, defaults to `IMAGENET_DEFAULT_STD`): + Standard deviation values to use when normalizing the image. Can be a single value or a list of values, one + for each channel. Can be overridden by the `image_std` parameter in the `preprocess` method. + do_convert_annotations (`bool`, *optional*, defaults to `True`): + Controls whether to convert the annotations to the format expected by the DETR model. Converts the + bounding boxes to the format `(center_x, center_y, width, height)` and in the range `[0, 1]`. + Can be overridden by the `do_convert_annotations` parameter in the `preprocess` method. + do_pad (`bool`, *optional*, defaults to `False`): + Controls whether to pad the image. Can be overridden by the `do_pad` parameter in the `preprocess` + method. If `True`, padding will be applied to the bottom and right of the image with zeros. + If `pad_size` is provided, the image will be padded to the specified dimensions. + Otherwise, the image will be padded to the maximum height and width of the batch. + pad_size (`dict[str, int]`, *optional*): + The size `{"height": int, "width" int}` to pad the images to. Must be larger than any image size + provided for preprocessing. If `pad_size` is not provided, images will be padded to the largest + height and width in the batch. + """ + + model_input_names = ["pixel_values", "pixel_mask"] + valid_kwargs = RTDetrImageProcessorKwargs + + def __init__( + self, + format: str | AnnotationFormat = AnnotationFormat.COCO_DETECTION, + do_resize: bool = True, + size: dict[str, int] | None = None, + resample: PILImageResampling = PILImageResampling.BILINEAR, + do_rescale: bool = True, + rescale_factor: int | float = 1 / 255, + do_normalize: bool = False, + image_mean: float | list[float] | None = None, + image_std: float | list[float] | None = None, + do_convert_annotations: bool = True, + do_pad: bool = False, + pad_size: dict[str, int] | None = None, + **kwargs, + ) -> None: + size = size if size is not None else {"height": 640, "width": 640} + size = get_size_dict(size, default_to_square=False) + + if do_convert_annotations is None: + do_convert_annotations = do_normalize + + super().__init__(**kwargs) + self.format = format + self.do_resize = do_resize + self.size = size + self.resample = resample + self.do_rescale = do_rescale + self.rescale_factor = rescale_factor + self.do_normalize = do_normalize + self.do_convert_annotations = do_convert_annotations + self.image_mean = image_mean if image_mean is not None else IMAGENET_DEFAULT_MEAN + self.image_std = image_std if image_std is not None else IMAGENET_DEFAULT_STD + self.do_pad = do_pad + self.pad_size = pad_size + + def prepare_annotation( + self, + image: np.ndarray, + target: dict, + format: AnnotationFormat | None = None, + return_segmentation_masks: bool | None = None, + masks_path: str | pathlib.Path | None = None, + input_data_format: str | ChannelDimension | None = None, + ) -> dict: + """ + Prepare an annotation for feeding into RTDETR model. + """ + format = format if format is not None else self.format + + if format == AnnotationFormat.COCO_DETECTION: + return_segmentation_masks = False if return_segmentation_masks is None else return_segmentation_masks + target = prepare_coco_detection_annotation( + image, target, return_segmentation_masks, input_data_format=input_data_format + ) + else: + raise ValueError(f"Format {format} is not supported.") + return target + + # Copied from transformers.models.detr.image_processing_detr.DetrImageProcessor.resize + def resize( + self, + image: np.ndarray, + size: dict[str, int], + resample: PILImageResampling = PILImageResampling.BILINEAR, + data_format: ChannelDimension | None = None, + input_data_format: str | ChannelDimension | None = None, + **kwargs, + ) -> np.ndarray: + """ + Resize the image to the given size. Size can be `min_size` (scalar) or `(height, width)` tuple. If size is an + int, smaller edge of the image will be matched to this number. + + Args: + image (`np.ndarray`): + Image to resize. + size (`dict[str, int]`): + Size of the image's `(height, width)` dimensions after resizing. Available options are: + - `{"height": int, "width": int}`: The image will be resized to the exact size `(height, width)`. + Do NOT keep the aspect ratio. + - `{"shortest_edge": int, "longest_edge": int}`: The image will be resized to a maximum size respecting + the aspect ratio and keeping the shortest edge less or equal to `shortest_edge` and the longest edge + less or equal to `longest_edge`. + - `{"max_height": int, "max_width": int}`: The image will be resized to the maximum size respecting the + aspect ratio and keeping the height less or equal to `max_height` and the width less or equal to + `max_width`. + resample (`PILImageResampling`, *optional*, defaults to `PILImageResampling.BILINEAR`): + Resampling filter to use if resizing the image. + data_format (`str` or `ChannelDimension`, *optional*): + The channel dimension format for the output image. If unset, the channel dimension format of the input + image is used. + input_data_format (`ChannelDimension` or `str`, *optional*): + The channel dimension format of the input image. If not provided, it will be inferred. + """ + size = get_size_dict(size, max_size=None, default_to_square=False) + if "shortest_edge" in size and "longest_edge" in size: + new_size = get_resize_output_image_size( + image, size["shortest_edge"], size["longest_edge"], input_data_format=input_data_format + ) + elif "max_height" in size and "max_width" in size: + new_size = get_image_size_for_max_height_width( + image, size["max_height"], size["max_width"], input_data_format=input_data_format + ) + elif "height" in size and "width" in size: + new_size = (size["height"], size["width"]) + else: + raise ValueError( + "Size must contain 'height' and 'width' keys or 'shortest_edge' and 'longest_edge' keys. Got" + f" {size.keys()}." + ) + image = resize( + image, + size=new_size, + resample=resample, + data_format=data_format, + input_data_format=input_data_format, + **kwargs, + ) + return image + + # Copied from transformers.models.detr.image_processing_detr.DetrImageProcessor.resize_annotation + def resize_annotation( + self, + annotation, + orig_size, + size, + resample: PILImageResampling = PILImageResampling.NEAREST, + ) -> dict: + """ + Resize the annotation to match the resized image. If size is an int, smaller edge of the mask will be matched + to this number. + """ + return resize_annotation(annotation, orig_size=orig_size, target_size=size, resample=resample) + + # Copied from transformers.models.detr.image_processing_detr.DetrImageProcessor.rescale + def rescale( + self, + image: np.ndarray, + rescale_factor: float, + data_format: str | ChannelDimension | None = None, + input_data_format: str | ChannelDimension | None = None, + ) -> np.ndarray: + """ + Rescale the image by the given factor. image = image * rescale_factor. + + Args: + image (`np.ndarray`): + Image to rescale. + rescale_factor (`float`): + The value to use for rescaling. + data_format (`str` or `ChannelDimension`, *optional*): + The channel dimension format for the output image. If unset, the channel dimension format of the input + image is used. Can be one of: + - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format. + - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format. + input_data_format (`str` or `ChannelDimension`, *optional*): + The channel dimension format for the input image. If unset, is inferred from the input image. Can be + one of: + - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format. + - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format. + """ + return rescale(image, rescale_factor, data_format=data_format, input_data_format=input_data_format) + + # Copied from transformers.models.detr.image_processing_detr.DetrImageProcessor.normalize_annotation + def normalize_annotation(self, annotation: dict, image_size: tuple[int, int]) -> dict: + """ + Normalize the boxes in the annotation from `[top_left_x, top_left_y, bottom_right_x, bottom_right_y]` to + `[center_x, center_y, width, height]` format and from absolute to relative pixel values. + """ + return normalize_annotation(annotation, image_size=image_size) + + # Copied from transformers.models.detr.image_processing_detr.DetrImageProcessor._update_annotation_for_padded_image + def _update_annotation_for_padded_image( + self, + annotation: dict, + input_image_size: tuple[int, int], + output_image_size: tuple[int, int], + padding, + update_bboxes, + ) -> dict: + """ + Update the annotation for a padded image. + """ + new_annotation = {} + new_annotation["size"] = output_image_size + + for key, value in annotation.items(): + if key == "masks": + masks = value + masks = pad( + masks, + padding, + mode=PaddingMode.CONSTANT, + constant_values=0, + input_data_format=ChannelDimension.FIRST, + ) + masks = safe_squeeze(masks, 1) + new_annotation["masks"] = masks + elif key == "boxes" and update_bboxes: + boxes = value + boxes *= np.asarray( + [ + input_image_size[1] / output_image_size[1], + input_image_size[0] / output_image_size[0], + input_image_size[1] / output_image_size[1], + input_image_size[0] / output_image_size[0], + ] + ) + new_annotation["boxes"] = boxes + elif key == "size": + new_annotation["size"] = output_image_size + else: + new_annotation[key] = value + return new_annotation + + # Copied from transformers.models.detr.image_processing_detr.DetrImageProcessor._pad_image + def _pad_image( + self, + image: np.ndarray, + output_size: tuple[int, int], + annotation: dict[str, Any] | None = None, + constant_values: float | Iterable[float] = 0, + data_format: ChannelDimension | None = None, + input_data_format: str | ChannelDimension | None = None, + update_bboxes: bool = True, + ) -> np.ndarray: + """ + Pad an image with zeros to the given size. + """ + input_height, input_width = get_image_size(image, channel_dim=input_data_format) + output_height, output_width = output_size + + pad_bottom = output_height - input_height + pad_right = output_width - input_width + padding = ((0, pad_bottom), (0, pad_right)) + padded_image = pad( + image, + padding, + mode=PaddingMode.CONSTANT, + constant_values=constant_values, + data_format=data_format, + input_data_format=input_data_format, + ) + if annotation is not None: + annotation = self._update_annotation_for_padded_image( + annotation, (input_height, input_width), (output_height, output_width), padding, update_bboxes + ) + return padded_image, annotation + + # Copied from transformers.models.detr.image_processing_detr.DetrImageProcessor.pad + def pad( + self, + images: list[np.ndarray], + annotations: AnnotationType | list[AnnotationType] | None = None, + constant_values: float | Iterable[float] = 0, + return_pixel_mask: bool = True, + return_tensors: str | TensorType | None = None, + data_format: ChannelDimension | None = None, + input_data_format: str | ChannelDimension | None = None, + update_bboxes: bool = True, + pad_size: dict[str, int] | None = None, + ) -> BatchFeature: + """ + Pads a batch of images to the bottom and right of the image with zeros to the size of largest height and width + in the batch and optionally returns their corresponding pixel mask. + + Args: + images (list[`np.ndarray`]): + Images to pad. + annotations (`AnnotationType` or `list[AnnotationType]`, *optional*): + Annotations to transform according to the padding that is applied to the images. + constant_values (`float` or `Iterable[float]`, *optional*): + The value to use for the padding if `mode` is `"constant"`. + return_pixel_mask (`bool`, *optional*, defaults to `True`): + Whether to return a pixel mask. + return_tensors (`str` or `TensorType`, *optional*): + The type of tensors to return. Can be one of: + - Unset: Return a list of `np.ndarray`. + - `TensorType.PYTORCH` or `'pt'`: Return a batch of type `torch.Tensor`. + - `TensorType.NUMPY` or `'np'`: Return a batch of type `np.ndarray`. + data_format (`str` or `ChannelDimension`, *optional*): + The channel dimension format of the image. If not provided, it will be the same as the input image. + input_data_format (`ChannelDimension` or `str`, *optional*): + The channel dimension format of the input image. If not provided, it will be inferred. + update_bboxes (`bool`, *optional*, defaults to `True`): + Whether to update the bounding boxes in the annotations to match the padded images. If the + bounding boxes have not been converted to relative coordinates and `(centre_x, centre_y, width, height)` + format, the bounding boxes will not be updated. + pad_size (`dict[str, int]`, *optional*): + The size `{"height": int, "width" int}` to pad the images to. Must be larger than any image size + provided for preprocessing. If `pad_size` is not provided, images will be padded to the largest + height and width in the batch. + """ + pad_size = pad_size if pad_size is not None else self.pad_size + if pad_size is not None: + padded_size = (pad_size["height"], pad_size["width"]) + else: + padded_size = get_max_height_width(images, input_data_format=input_data_format) + + annotation_list = annotations if annotations is not None else [None] * len(images) + padded_images = [] + padded_annotations = [] + for image, annotation in zip(images, annotation_list): + padded_image, padded_annotation = self._pad_image( + image, + padded_size, + annotation, + constant_values=constant_values, + data_format=data_format, + input_data_format=input_data_format, + update_bboxes=update_bboxes, + ) + padded_images.append(padded_image) + padded_annotations.append(padded_annotation) + + data = {"pixel_values": padded_images} + + if return_pixel_mask: + masks = [ + make_pixel_mask(image=image, output_size=padded_size, input_data_format=input_data_format) + for image in images + ] + data["pixel_mask"] = masks + + encoded_inputs = BatchFeature(data=data, tensor_type=return_tensors) + + if annotations is not None: + encoded_inputs["labels"] = [ + BatchFeature(annotation, tensor_type=return_tensors) for annotation in padded_annotations + ] + + return encoded_inputs + + @filter_out_non_signature_kwargs() + def preprocess( + self, + images: ImageInput, + annotations: AnnotationType | list[AnnotationType] | None = None, + return_segmentation_masks: bool | None = None, + masks_path: str | pathlib.Path | None = None, + do_resize: bool | None = None, + size: dict[str, int] | None = None, + resample=None, # PILImageResampling + do_rescale: bool | None = None, + rescale_factor: int | float | None = None, + do_normalize: bool | None = None, + do_convert_annotations: bool | None = None, + image_mean: float | list[float] | None = None, + image_std: float | list[float] | None = None, + do_pad: bool | None = None, + format: str | AnnotationFormat | None = None, + return_tensors: TensorType | str | None = None, + data_format: str | ChannelDimension = ChannelDimension.FIRST, + input_data_format: str | ChannelDimension | None = None, + pad_size: dict[str, int] | None = None, + ) -> BatchFeature: + """ + Preprocess an image or a batch of images so that it can be used by the model. + + Args: + images (`ImageInput`): + Image or batch of images to preprocess. Expects a single or batch of images with pixel values ranging + from 0 to 255. If passing in images with pixel values between 0 and 1, set `do_rescale=False`. + annotations (`AnnotationType` or `list[AnnotationType]`, *optional*): + List of annotations associated with the image or batch of images. If annotation is for object + detection, the annotations should be a dictionary with the following keys: + - "image_id" (`int`): The image id. + - "annotations" (`list[Dict]`): List of annotations for an image. Each annotation should be a + dictionary. An image can have no annotations, in which case the list should be empty. + If annotation is for segmentation, the annotations should be a dictionary with the following keys: + - "image_id" (`int`): The image id. + - "segments_info" (`list[Dict]`): List of segments for an image. Each segment should be a dictionary. + An image can have no segments, in which case the list should be empty. + - "file_name" (`str`): The file name of the image. + return_segmentation_masks (`bool`, *optional*, defaults to self.return_segmentation_masks): + Whether to return segmentation masks. + masks_path (`str` or `pathlib.Path`, *optional*): + Path to the directory containing the segmentation masks. + do_resize (`bool`, *optional*, defaults to self.do_resize): + Whether to resize the image. + size (`dict[str, int]`, *optional*, defaults to self.size): + Size of the image's `(height, width)` dimensions after resizing. Available options are: + - `{"height": int, "width": int}`: The image will be resized to the exact size `(height, width)`. + Do NOT keep the aspect ratio. + - `{"shortest_edge": int, "longest_edge": int}`: The image will be resized to a maximum size respecting + the aspect ratio and keeping the shortest edge less or equal to `shortest_edge` and the longest edge + less or equal to `longest_edge`. + - `{"max_height": int, "max_width": int}`: The image will be resized to the maximum size respecting the + aspect ratio and keeping the height less or equal to `max_height` and the width less or equal to + `max_width`. + resample (`PILImageResampling`, *optional*, defaults to self.resample): + Resampling filter to use when resizing the image. + do_rescale (`bool`, *optional*, defaults to self.do_rescale): + Whether to rescale the image. + rescale_factor (`float`, *optional*, defaults to self.rescale_factor): + Rescale factor to use when rescaling the image. + do_normalize (`bool`, *optional*, defaults to self.do_normalize): + Whether to normalize the image. + do_convert_annotations (`bool`, *optional*, defaults to self.do_convert_annotations): + Whether to convert the annotations to the format expected by the model. Converts the bounding + boxes from the format `(top_left_x, top_left_y, width, height)` to `(center_x, center_y, width, height)` + and in relative coordinates. + image_mean (`float` or `list[float]`, *optional*, defaults to self.image_mean): + Mean to use when normalizing the image. + image_std (`float` or `list[float]`, *optional*, defaults to self.image_std): + Standard deviation to use when normalizing the image. + do_pad (`bool`, *optional*, defaults to self.do_pad): + Whether to pad the image. If `True`, padding will be applied to the bottom and right of + the image with zeros. If `pad_size` is provided, the image will be padded to the specified + dimensions. Otherwise, the image will be padded to the maximum height and width of the batch. + format (`str` or `AnnotationFormat`, *optional*, defaults to self.format): + Format of the annotations. + return_tensors (`str` or `TensorType`, *optional*, defaults to self.return_tensors): + Type of tensors to return. If `None`, will return the list of images. + data_format (`ChannelDimension` or `str`, *optional*, defaults to `ChannelDimension.FIRST`): + The channel dimension format for the output image. Can be one of: + - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format. + - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format. + - Unset: Use the channel dimension format of the input image. + input_data_format (`ChannelDimension` or `str`, *optional*): + The channel dimension format for the input image. If unset, the channel dimension format is inferred + from the input image. Can be one of: + - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format. + - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format. + - `"none"` or `ChannelDimension.NONE`: image in (height, width) format. + pad_size (`dict[str, int]`, *optional*): + The size `{"height": int, "width" int}` to pad the images to. Must be larger than any image size + provided for preprocessing. If `pad_size` is not provided, images will be padded to the largest + height and width in the batch. + """ + do_resize = self.do_resize if do_resize is None else do_resize + size = self.size if size is None else size + size = get_size_dict(size=size, default_to_square=True) + resample = self.resample if resample is None else resample + do_rescale = self.do_rescale if do_rescale is None else do_rescale + rescale_factor = self.rescale_factor if rescale_factor is None else rescale_factor + do_normalize = self.do_normalize if do_normalize is None else do_normalize + image_mean = self.image_mean if image_mean is None else image_mean + image_std = self.image_std if image_std is None else image_std + do_convert_annotations = ( + self.do_convert_annotations if do_convert_annotations is None else do_convert_annotations + ) + do_pad = self.do_pad if do_pad is None else do_pad + pad_size = self.pad_size if pad_size is None else pad_size + format = self.format if format is None else format + + images = make_flat_list_of_images(images) + + if not valid_images(images): + raise ValueError("Invalid image type. Must be of type PIL.Image.Image, numpy.ndarray, or torch.Tensor.") + + # Here, the pad() method pads to the maximum of (width, height). It does not need to be validated. + + validate_preprocess_arguments( + do_rescale=do_rescale, + rescale_factor=rescale_factor, + do_normalize=do_normalize, + image_mean=image_mean, + image_std=image_std, + do_resize=do_resize, + size=size, + resample=resample, + ) + + if annotations is not None and isinstance(annotations, dict): + annotations = [annotations] + + if annotations is not None and len(images) != len(annotations): + raise ValueError( + f"The number of images ({len(images)}) and annotations ({len(annotations)}) do not match." + ) + + format = AnnotationFormat(format) + if annotations is not None: + validate_annotations(format, SUPPORTED_ANNOTATION_FORMATS, annotations) + + images = make_flat_list_of_images(images) + if not valid_images(images): + raise ValueError("Invalid image type. Must be of type PIL.Image.Image, numpy.ndarray, or torch.Tensor") + + # All transformations expect numpy arrays + images = [to_numpy_array(image) for image in images] + + if do_rescale and is_scaled_image(images[0]): + logger.warning_once( + "It looks like you are trying to rescale already rescaled images. If the input" + " images have pixel values between 0 and 1, set `do_rescale=False` to avoid rescaling them again." + ) + + if input_data_format is None: + # We assume that all images have the same channel dimension format. + input_data_format = infer_channel_dimension_format(images[0]) + + # prepare (COCO annotations as a list of Dict -> DETR target as a single Dict per image) + if annotations is not None: + prepared_images = [] + prepared_annotations = [] + for image, target in zip(images, annotations): + target = self.prepare_annotation( + image, + target, + format, + return_segmentation_masks=return_segmentation_masks, + masks_path=masks_path, + input_data_format=input_data_format, + ) + prepared_images.append(image) + prepared_annotations.append(target) + images = prepared_images + annotations = prepared_annotations + del prepared_images, prepared_annotations + + # transformations + if do_resize: + if annotations is not None: + resized_images, resized_annotations = [], [] + for image, target in zip(images, annotations): + orig_size = get_image_size(image, input_data_format) + resized_image = self.resize( + image, size=size, resample=resample, input_data_format=input_data_format + ) + resized_annotation = self.resize_annotation( + target, orig_size, get_image_size(resized_image, input_data_format) + ) + resized_images.append(resized_image) + resized_annotations.append(resized_annotation) + images = resized_images + annotations = resized_annotations + del resized_images, resized_annotations + else: + images = [ + self.resize(image, size=size, resample=resample, input_data_format=input_data_format) + for image in images + ] + + if do_rescale: + images = [self.rescale(image, rescale_factor, input_data_format=input_data_format) for image in images] + + if do_normalize: + images = [ + self.normalize(image, image_mean, image_std, input_data_format=input_data_format) for image in images + ] + + if do_convert_annotations and annotations is not None: + annotations = [ + self.normalize_annotation(annotation, get_image_size(image, input_data_format)) + for annotation, image in zip(annotations, images) + ] + + if do_pad: + # Pads images and returns their mask: {'pixel_values': ..., 'pixel_mask': ...} + encoded_inputs = self.pad( + images, + annotations=annotations, + return_pixel_mask=True, + data_format=data_format, + input_data_format=input_data_format, + update_bboxes=do_convert_annotations, + return_tensors=return_tensors, + pad_size=pad_size, + ) + else: + images = [ + to_channel_dimension_format(image, data_format, input_channel_dim=input_data_format) + for image in images + ] + encoded_inputs = BatchFeature(data={"pixel_values": images}, tensor_type=return_tensors) + if annotations is not None: + encoded_inputs["labels"] = [ + BatchFeature(annotation, tensor_type=return_tensors) for annotation in annotations + ] + + return encoded_inputs + + def post_process_object_detection( + self, + outputs, + threshold: float = 0.5, + target_sizes: TensorType | list[tuple] | None = None, + use_focal_loss: bool = True, + ): + """ + Converts the raw output of [`DetrForObjectDetection`] into final bounding boxes in (top_left_x, top_left_y, + bottom_right_x, bottom_right_y) format. Only supports PyTorch. + + Args: + outputs ([`DetrObjectDetectionOutput`]): + Raw outputs of the model. + threshold (`float`, *optional*, defaults to 0.5): + Score threshold to keep object detection predictions. + target_sizes (`torch.Tensor` or `list[tuple[int, int]]`, *optional*): + Tensor of shape `(batch_size, 2)` or list of tuples (`tuple[int, int]`) containing the target size + `(height, width)` of each image in the batch. If unset, predictions will not be resized. + use_focal_loss (`bool` defaults to `True`): + Variable informing if the focal loss was used to predict the outputs. If `True`, a sigmoid is applied + to compute the scores of each detection, otherwise, a softmax function is used. + + Returns: + `list[Dict]`: A list of dictionaries, each dictionary containing the scores, labels and boxes for an image + in the batch as predicted by the model. + """ + requires_backends(self, ["torch"]) + out_logits, out_bbox = outputs.logits, outputs.pred_boxes + # convert from relative cxcywh to absolute xyxy + boxes = center_to_corners_format(out_bbox) + if target_sizes is not None: + if len(out_logits) != len(target_sizes): + raise ValueError( + "Make sure that you pass in as many target sizes as the batch dimension of the logits" + ) + if isinstance(target_sizes, list): + img_h, img_w = torch.as_tensor(target_sizes).unbind(1) + else: + img_h, img_w = target_sizes.unbind(1) + scale_fct = torch.stack([img_w, img_h, img_w, img_h], dim=1).to(boxes.device) + boxes = boxes * scale_fct[:, None, :] + + num_top_queries = out_logits.shape[1] + num_classes = out_logits.shape[2] + + if use_focal_loss: + scores = torch.nn.functional.sigmoid(out_logits) + scores, index = torch.topk(scores.flatten(1), num_top_queries, axis=-1) + labels = index % num_classes + index = index // num_classes + boxes = boxes.gather(dim=1, index=index.unsqueeze(-1).repeat(1, 1, boxes.shape[-1])) + else: + scores = torch.nn.functional.softmax(out_logits)[:, :, :-1] + scores, labels = scores.max(dim=-1) + if scores.shape[1] > num_top_queries: + scores, index = torch.topk(scores, num_top_queries, dim=-1) + labels = torch.gather(labels, dim=1, index=index) + boxes = torch.gather(boxes, dim=1, index=index.unsqueeze(-1).tile(1, 1, boxes.shape[-1])) + + results = [] + for score, label, box in zip(scores, labels, boxes): + results.append( + { + "scores": score[score > threshold], + "labels": label[score > threshold], + "boxes": box[score > threshold], + } + ) + + return results + + +__all__ = ["RTDetrImageProcessor"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/rt_detr/image_processing_rt_detr_fast.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/rt_detr/image_processing_rt_detr_fast.py new file mode 100644 index 0000000000000000000000000000000000000000..9c30d94685a7af1efc573eafef0bb3d14f18a66d --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/rt_detr/image_processing_rt_detr_fast.py @@ -0,0 +1,528 @@ +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# This file was automatically generated from src/transformers/models/rt_detr/modular_rt_detr.py. +# Do NOT edit this file manually as any edits will be overwritten by the generation of +# the file from the modular. If any change should be done, please apply the change to the +# modular_rt_detr.py file directly. One of our CI enforces this. +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# Copyright 2024 Baidu Inc and The HuggingFace Inc. team. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +import pathlib +from typing import Any, Optional + +import torch +import torchvision.transforms.v2.functional as tvF + +from ...image_processing_utils import BatchFeature +from ...image_processing_utils_fast import ( + BaseImageProcessorFast, + SizeDict, + get_image_size_for_max_height_width, + get_max_height_width, + safe_squeeze, +) +from ...image_transforms import center_to_corners_format, corners_to_center_format +from ...image_utils import ( + IMAGENET_DEFAULT_MEAN, + IMAGENET_DEFAULT_STD, + AnnotationFormat, + AnnotationType, + ChannelDimension, + PILImageResampling, + get_image_size, + validate_annotations, +) +from ...processing_utils import Unpack +from ...utils import TensorType, auto_docstring, requires_backends +from ...utils.import_utils import requires +from .image_processing_rt_detr import RTDetrImageProcessorKwargs, get_size_with_aspect_ratio + + +SUPPORTED_ANNOTATION_FORMATS = (AnnotationFormat.COCO_DETECTION, AnnotationFormat.COCO_PANOPTIC) + + +def prepare_coco_detection_annotation( + image, + target, + return_segmentation_masks: bool = False, + input_data_format: ChannelDimension | str | None = None, +): + """ + Convert the target in COCO format into the format expected by RT-DETR. + """ + image_height, image_width = image.size()[-2:] + + image_id = target["image_id"] + image_id = torch.as_tensor([image_id], dtype=torch.int64, device=image.device) + + # Get all COCO annotations for the given image. + annotations = target["annotations"] + classes = [] + area = [] + boxes = [] + keypoints = [] + for obj in annotations: + if "iscrowd" not in obj or obj["iscrowd"] == 0: + classes.append(obj["category_id"]) + area.append(obj["area"]) + boxes.append(obj["bbox"]) + if "keypoints" in obj: + keypoints.append(obj["keypoints"]) + + classes = torch.as_tensor(classes, dtype=torch.int64, device=image.device) + area = torch.as_tensor(area, dtype=torch.float32, device=image.device) + iscrowd = torch.zeros_like(classes, dtype=torch.int64, device=image.device) + # guard against no boxes via resizing + boxes = torch.as_tensor(boxes, dtype=torch.float32, device=image.device).reshape(-1, 4) + boxes[:, 2:] += boxes[:, :2] + boxes[:, 0::2] = boxes[:, 0::2].clip(min=0, max=image_width) + boxes[:, 1::2] = boxes[:, 1::2].clip(min=0, max=image_height) + + keep = (boxes[:, 3] > boxes[:, 1]) & (boxes[:, 2] > boxes[:, 0]) + + new_target = { + "image_id": image_id, + "class_labels": classes[keep], + "boxes": boxes[keep], + "area": area[keep], + "iscrowd": iscrowd[keep], + "orig_size": torch.as_tensor([int(image_height), int(image_width)], dtype=torch.int64, device=image.device), + } + + if keypoints: + keypoints = torch.as_tensor(keypoints, dtype=torch.float32, device=image.device) + # Apply the keep mask here to filter the relevant annotations + keypoints = keypoints[keep] + num_keypoints = keypoints.shape[0] + keypoints = keypoints.reshape((-1, 3)) if num_keypoints else keypoints + new_target["keypoints"] = keypoints + + return new_target + + +@auto_docstring +@requires(backends=("torchvision", "torch")) +class RTDetrImageProcessorFast(BaseImageProcessorFast): + resample = PILImageResampling.BILINEAR + image_mean = IMAGENET_DEFAULT_MEAN + image_std = IMAGENET_DEFAULT_STD + format = AnnotationFormat.COCO_DETECTION + do_resize = True + do_rescale = True + do_normalize = False + do_pad = False + size = {"height": 640, "width": 640} + default_to_square = False + model_input_names = ["pixel_values", "pixel_mask"] + valid_kwargs = RTDetrImageProcessorKwargs + do_convert_annotations = True + + def __init__(self, **kwargs: Unpack[RTDetrImageProcessorKwargs]) -> None: + # Backwards compatibility + do_convert_annotations = kwargs.get("do_convert_annotations") + do_normalize = kwargs.get("do_normalize") + if do_convert_annotations is None and getattr(self, "do_convert_annotations", None) is None: + self.do_convert_annotations = do_normalize if do_normalize is not None else self.do_normalize + + super().__init__(**kwargs) + + def prepare_annotation( + self, + image: torch.Tensor, + target: dict, + format: AnnotationFormat | None = None, + return_segmentation_masks: bool | None = None, + masks_path: str | pathlib.Path | None = None, + input_data_format: str | ChannelDimension | None = None, + ) -> dict: + """ + Prepare an annotation for feeding into RT_DETR model. + """ + format = format if format is not None else self.format + + if format == AnnotationFormat.COCO_DETECTION: + return_segmentation_masks = False if return_segmentation_masks is None else return_segmentation_masks + target = prepare_coco_detection_annotation( + image, target, return_segmentation_masks, input_data_format=input_data_format + ) + else: + raise ValueError(f"Format {format} is not supported.") + return target + + def resize( + self, + image: torch.Tensor, + size: SizeDict, + interpolation: Optional["tvF.InterpolationMode"] = None, + **kwargs, + ) -> torch.Tensor: + """ + Resize the image to the given size. Size can be `min_size` (scalar) or `(height, width)` tuple. If size is an + int, smaller edge of the image will be matched to this number. + + Args: + image (`torch.Tensor`): + Image to resize. + size (`SizeDict`): + Size of the image's `(height, width)` dimensions after resizing. Available options are: + - `{"height": int, "width": int}`: The image will be resized to the exact size `(height, width)`. + Do NOT keep the aspect ratio. + - `{"shortest_edge": int, "longest_edge": int}`: The image will be resized to a maximum size respecting + the aspect ratio and keeping the shortest edge less or equal to `shortest_edge` and the longest edge + less or equal to `longest_edge`. + - `{"max_height": int, "max_width": int}`: The image will be resized to the maximum size respecting the + aspect ratio and keeping the height less or equal to `max_height` and the width less or equal to + `max_width`. + interpolation (`InterpolationMode`, *optional*, defaults to `InterpolationMode.BILINEAR`): + Resampling filter to use if resizing the image. + """ + interpolation = interpolation if interpolation is not None else tvF.InterpolationMode.BILINEAR + if size.shortest_edge and size.longest_edge: + # Resize the image so that the shortest edge or the longest edge is of the given size + # while maintaining the aspect ratio of the original image. + new_size = get_size_with_aspect_ratio( + image.size()[-2:], + size["shortest_edge"], + size["longest_edge"], + ) + elif size.max_height and size.max_width: + new_size = get_image_size_for_max_height_width(image.size()[-2:], size["max_height"], size["max_width"]) + elif size.height and size.width: + new_size = (size["height"], size["width"]) + else: + raise ValueError( + "Size must contain 'height' and 'width' keys or 'shortest_edge' and 'longest_edge' keys. Got" + f" {size.keys()}." + ) + + image = tvF.resize( + image, + size=new_size, + interpolation=interpolation, + **kwargs, + ) + return image + + def resize_annotation( + self, + annotation: dict[str, Any], + orig_size: tuple[int, int], + target_size: tuple[int, int], + threshold: float = 0.5, + interpolation: Optional["tvF.InterpolationMode"] = None, + ): + """ + Resizes an annotation to a target size. + + Args: + annotation (`dict[str, Any]`): + The annotation dictionary. + orig_size (`tuple[int, int]`): + The original size of the input image. + target_size (`tuple[int, int]`): + The target size of the image, as returned by the preprocessing `resize` step. + threshold (`float`, *optional*, defaults to 0.5): + The threshold used to binarize the segmentation masks. + resample (`InterpolationMode`, defaults to `tvF.InterpolationMode.NEAREST_EXACT`): + The resampling filter to use when resizing the masks. + """ + interpolation = interpolation if interpolation is not None else tvF.InterpolationMode.NEAREST_EXACT + ratio_height, ratio_width = [target / orig for target, orig in zip(target_size, orig_size)] + + new_annotation = {} + new_annotation["size"] = target_size + + for key, value in annotation.items(): + if key == "boxes": + boxes = value + scaled_boxes = boxes * torch.as_tensor( + [ratio_width, ratio_height, ratio_width, ratio_height], dtype=torch.float32, device=boxes.device + ) + new_annotation["boxes"] = scaled_boxes + elif key == "area": + area = value + scaled_area = area * (ratio_width * ratio_height) + new_annotation["area"] = scaled_area + elif key == "masks": + masks = value[:, None] + masks = [tvF.resize(mask, target_size, interpolation=interpolation) for mask in masks] + masks = torch.stack(masks).to(torch.float32) + masks = masks[:, 0] > threshold + new_annotation["masks"] = masks + elif key == "size": + new_annotation["size"] = target_size + else: + new_annotation[key] = value + + return new_annotation + + def normalize_annotation(self, annotation: dict, image_size: tuple[int, int]) -> dict: + image_height, image_width = image_size + norm_annotation = {} + for key, value in annotation.items(): + if key == "boxes": + boxes = value + boxes = corners_to_center_format(boxes) + boxes /= torch.as_tensor( + [image_width, image_height, image_width, image_height], dtype=torch.float32, device=boxes.device + ) + norm_annotation[key] = boxes + else: + norm_annotation[key] = value + return norm_annotation + + def _update_annotation_for_padded_image( + self, + annotation: dict, + input_image_size: tuple[int, int], + output_image_size: tuple[int, int], + padding, + update_bboxes, + ) -> dict: + """ + Update the annotation for a padded image. + """ + new_annotation = {} + new_annotation["size"] = output_image_size + ratio_height, ratio_width = (input / output for output, input in zip(output_image_size, input_image_size)) + + for key, value in annotation.items(): + if key == "masks": + masks = value + masks = tvF.pad( + masks, + padding, + fill=0, + ) + masks = safe_squeeze(masks, 1) + new_annotation["masks"] = masks + elif key == "boxes" and update_bboxes: + boxes = value + boxes *= torch.as_tensor([ratio_width, ratio_height, ratio_width, ratio_height], device=boxes.device) + new_annotation["boxes"] = boxes + elif key == "size": + new_annotation["size"] = output_image_size + else: + new_annotation[key] = value + return new_annotation + + def pad( + self, + image: torch.Tensor, + padded_size: tuple[int, int], + annotation: dict[str, Any] | None = None, + update_bboxes: bool = True, + fill: int = 0, + ): + original_size = image.size()[-2:] + padding_bottom = padded_size[0] - original_size[0] + padding_right = padded_size[1] - original_size[1] + if padding_bottom < 0 or padding_right < 0: + raise ValueError( + f"Padding dimensions are negative. Please make sure that the padded size is larger than the " + f"original size. Got padded size: {padded_size}, original size: {original_size}." + ) + if original_size != padded_size: + padding = [0, 0, padding_right, padding_bottom] + image = tvF.pad(image, padding, fill=fill) + if annotation is not None: + annotation = self._update_annotation_for_padded_image( + annotation, original_size, padded_size, padding, update_bboxes + ) + + # Make a pixel mask for the image, where 1 indicates a valid pixel and 0 indicates padding. + pixel_mask = torch.zeros(padded_size, dtype=torch.int64, device=image.device) + pixel_mask[: original_size[0], : original_size[1]] = 1 + + return image, pixel_mask, annotation + + def _preprocess( + self, + images: list["torch.Tensor"], + annotations: AnnotationType | list[AnnotationType] | None, + masks_path: str | pathlib.Path | None, + return_segmentation_masks: bool, + do_resize: bool, + size: SizeDict, + interpolation: Optional["tvF.InterpolationMode"], + do_rescale: bool, + rescale_factor: float, + do_normalize: bool, + do_convert_annotations: bool, + image_mean: float | list[float] | None, + image_std: float | list[float] | None, + do_pad: bool, + pad_size: SizeDict | None, + format: str | AnnotationFormat | None, + return_tensors: str | TensorType | None, + **kwargs, + ) -> BatchFeature: + """ + Preprocess an image or a batch of images so that it can be used by the model. + """ + + if annotations is not None and isinstance(annotations, dict): + annotations = [annotations] + + if annotations is not None and len(images) != len(annotations): + raise ValueError( + f"The number of images ({len(images)}) and annotations ({len(annotations)}) do not match." + ) + + format = AnnotationFormat(format) + if annotations is not None: + validate_annotations(format, SUPPORTED_ANNOTATION_FORMATS, annotations) + + data = {} + processed_images = [] + processed_annotations = [] + pixel_masks = [] # Initialize pixel_masks here + for image, annotation in zip(images, annotations if annotations is not None else [None] * len(images)): + # prepare (COCO annotations as a list of Dict -> DETR target as a single Dict per image) + if annotations is not None: + annotation = self.prepare_annotation( + image, + annotation, + format, + return_segmentation_masks=return_segmentation_masks, + masks_path=masks_path, + input_data_format=ChannelDimension.FIRST, + ) + + if do_resize: + resized_image = self.resize(image, size=size, interpolation=interpolation) + if annotations is not None: + annotation = self.resize_annotation( + annotation, + orig_size=image.size()[-2:], + target_size=resized_image.size()[-2:], + ) + image = resized_image + # Fused rescale and normalize + image = self.rescale_and_normalize(image, do_rescale, rescale_factor, do_normalize, image_mean, image_std) + if do_convert_annotations and annotations is not None: + annotation = self.normalize_annotation(annotation, get_image_size(image, ChannelDimension.FIRST)) + + processed_images.append(image) + processed_annotations.append(annotation) + images = processed_images + annotations = processed_annotations if annotations is not None else None + + if do_pad: + # depends on all resized image shapes so we need another loop + if pad_size is not None: + padded_size = (pad_size.height, pad_size.width) + else: + padded_size = get_max_height_width(images) + + padded_images = [] + padded_annotations = [] + for image, annotation in zip(images, annotations if annotations is not None else [None] * len(images)): + # Pads images and returns their mask: {'pixel_values': ..., 'pixel_mask': ...} + if padded_size == image.size()[-2:]: + padded_images.append(image) + pixel_masks.append(torch.ones(padded_size, dtype=torch.int64, device=image.device)) + padded_annotations.append(annotation) + continue + image, pixel_mask, annotation = self.pad( + image, padded_size, annotation=annotation, update_bboxes=do_convert_annotations + ) + padded_images.append(image) + padded_annotations.append(annotation) + pixel_masks.append(pixel_mask) + images = padded_images + annotations = padded_annotations if annotations is not None else None + data.update({"pixel_mask": torch.stack(pixel_masks, dim=0)}) + + data.update({"pixel_values": torch.stack(images, dim=0)}) + encoded_inputs = BatchFeature(data, tensor_type=return_tensors) + if annotations is not None: + encoded_inputs["labels"] = [ + BatchFeature(annotation, tensor_type=return_tensors) for annotation in annotations + ] + return encoded_inputs + + def post_process_object_detection( + self, + outputs, + threshold: float = 0.5, + target_sizes: TensorType | list[tuple] = None, + use_focal_loss: bool = True, + ): + """ + Converts the raw output of [`DetrForObjectDetection`] into final bounding boxes in (top_left_x, top_left_y, + bottom_right_x, bottom_right_y) format. Only supports PyTorch. + + Args: + outputs ([`DetrObjectDetectionOutput`]): + Raw outputs of the model. + threshold (`float`, *optional*, defaults to 0.5): + Score threshold to keep object detection predictions. + target_sizes (`torch.Tensor` or `list[tuple[int, int]]`, *optional*): + Tensor of shape `(batch_size, 2)` or list of tuples (`tuple[int, int]`) containing the target size + `(height, width)` of each image in the batch. If unset, predictions will not be resized. + use_focal_loss (`bool` defaults to `True`): + Variable informing if the focal loss was used to predict the outputs. If `True`, a sigmoid is applied + to compute the scores of each detection, otherwise, a softmax function is used. + + Returns: + `list[Dict]`: A list of dictionaries, each dictionary containing the scores, labels and boxes for an image + in the batch as predicted by the model. + """ + requires_backends(self, ["torch"]) + out_logits, out_bbox = outputs.logits, outputs.pred_boxes + # convert from relative cxcywh to absolute xyxy + boxes = center_to_corners_format(out_bbox) + if target_sizes is not None: + if len(out_logits) != len(target_sizes): + raise ValueError( + "Make sure that you pass in as many target sizes as the batch dimension of the logits" + ) + if isinstance(target_sizes, list): + img_h, img_w = torch.as_tensor(target_sizes).unbind(1) + else: + img_h, img_w = target_sizes.unbind(1) + scale_fct = torch.stack([img_w, img_h, img_w, img_h], dim=1).to(boxes.device) + boxes = boxes * scale_fct[:, None, :] + + num_top_queries = out_logits.shape[1] + num_classes = out_logits.shape[2] + + if use_focal_loss: + scores = torch.nn.functional.sigmoid(out_logits) + scores, index = torch.topk(scores.flatten(1), num_top_queries, axis=-1) + labels = index % num_classes + index = index // num_classes + boxes = boxes.gather(dim=1, index=index.unsqueeze(-1).repeat(1, 1, boxes.shape[-1])) + else: + scores = torch.nn.functional.softmax(out_logits)[:, :, :-1] + scores, labels = scores.max(dim=-1) + if scores.shape[1] > num_top_queries: + scores, index = torch.topk(scores, num_top_queries, dim=-1) + labels = torch.gather(labels, dim=1, index=index) + boxes = torch.gather(boxes, dim=1, index=index.unsqueeze(-1).tile(1, 1, boxes.shape[-1])) + + results = [] + for score, label, box in zip(scores, labels, boxes): + results.append( + { + "scores": score[score > threshold], + "labels": label[score > threshold], + "boxes": box[score > threshold], + } + ) + + return results + + +__all__ = ["RTDetrImageProcessorFast"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/rt_detr/modeling_rt_detr.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/rt_detr/modeling_rt_detr.py new file mode 100644 index 0000000000000000000000000000000000000000..182d4b2c054a151401738a50d6bd80fa846b04a3 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/rt_detr/modeling_rt_detr.py @@ -0,0 +1,1841 @@ +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# This file was automatically generated from src/transformers/models/rt_detr/modular_rt_detr.py. +# Do NOT edit this file manually as any edits will be overwritten by the generation of +# the file from the modular. If any change should be done, please apply the change to the +# modular_rt_detr.py file directly. One of our CI enforces this. +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# Copyright 2024 Baidu Inc and The HuggingFace Inc. team. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +import math +import warnings +from collections.abc import Callable +from dataclasses import dataclass + +import torch +import torch.nn.functional as F +from torch import Tensor, nn + +from ... import initialization as init +from ...activations import ACT2CLS, ACT2FN +from ...backbone_utils import load_backbone +from ...image_transforms import center_to_corners_format, corners_to_center_format +from ...integrations import use_kernel_forward_from_hub +from ...modeling_outputs import BaseModelOutput +from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel +from ...processing_utils import Unpack +from ...pytorch_utils import compile_compatible_method_lru_cache +from ...utils import ModelOutput, TransformersKwargs, auto_docstring, torch_compilable_check, torch_int +from ...utils.generic import can_return_tuple, merge_with_config_defaults +from ...utils.output_capturing import capture_outputs +from .configuration_rt_detr import RTDetrConfig + + +@dataclass +@auto_docstring( + custom_intro=""" + Base class for outputs of the RTDetrDecoder. This class adds two attributes to + BaseModelOutputWithCrossAttentions, namely: + - a stacked tensor of intermediate decoder hidden states (i.e. the output of each decoder layer) + - a stacked tensor of intermediate reference points. + """ +) +class RTDetrDecoderOutput(ModelOutput): + r""" + intermediate_hidden_states (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, hidden_size)`): + Stacked intermediate hidden states (output of each layer of the decoder). + intermediate_logits (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, sequence_length, config.num_labels)`): + Stacked intermediate logits (logits of each layer of the decoder). + intermediate_reference_points (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, sequence_length, hidden_size)`): + Stacked intermediate reference points (reference points of each layer of the decoder). + intermediate_predicted_corners (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, 4)`): + Stacked intermediate predicted corners (predicted corners of each layer of the decoder). + initial_reference_points (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, 4)`): + Stacked initial reference points (initial reference points of each layer of the decoder). + cross_attentions (`tuple(torch.FloatTensor)`, *optional*, returned when `output_attentions=True` and `config.add_cross_attention=True` is passed or when `config.output_attentions=True`): + Tuple of `torch.FloatTensor` (one for each layer) of shape `(batch_size, num_heads, sequence_length, + sequence_length)`. Attentions weights of the decoder's cross-attention layer, after the attention softmax, + used to compute the weighted average in the cross-attention heads. + """ + + last_hidden_state: torch.FloatTensor | None = None + intermediate_hidden_states: torch.FloatTensor | None = None + intermediate_logits: torch.FloatTensor | None = None + intermediate_reference_points: torch.FloatTensor | None = None + intermediate_predicted_corners: torch.FloatTensor | None = None + initial_reference_points: torch.FloatTensor | None = None + hidden_states: tuple[torch.FloatTensor] | None = None + attentions: tuple[torch.FloatTensor] | None = None + cross_attentions: tuple[torch.FloatTensor] | None = None + + +@dataclass +@auto_docstring( + custom_intro=""" + Base class for outputs of the RT-DETR encoder-decoder model. + """ +) +class RTDetrModelOutput(ModelOutput): + r""" + last_hidden_state (`torch.FloatTensor` of shape `(batch_size, num_queries, hidden_size)`): + Sequence of hidden-states at the output of the last layer of the decoder of the model. + intermediate_hidden_states (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, hidden_size)`): + Stacked intermediate hidden states (output of each layer of the decoder). + intermediate_logits (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, sequence_length, config.num_labels)`): + Stacked intermediate logits (logits of each layer of the decoder). + intermediate_reference_points (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, 4)`): + Stacked intermediate reference points (reference points of each layer of the decoder). + intermediate_predicted_corners (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, 4)`): + Stacked intermediate predicted corners (predicted corners of each layer of the decoder). + initial_reference_points (`torch.FloatTensor` of shape `(batch_size, num_queries, 4)`): + Initial reference points used for the first decoder layer. + init_reference_points (`torch.FloatTensor` of shape `(batch_size, num_queries, 4)`): + Initial reference points sent through the Transformer decoder. + enc_topk_logits (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.num_labels)`): + Predicted bounding boxes scores where the top `config.two_stage_num_proposals` scoring bounding boxes are + picked as region proposals in the encoder stage. Output of bounding box binary classification (i.e. + foreground and background). + enc_topk_bboxes (`torch.FloatTensor` of shape `(batch_size, sequence_length, 4)`): + Logits of predicted bounding boxes coordinates in the encoder stage. + enc_outputs_class (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.num_labels)`, *optional*, returned when `config.with_box_refine=True` and `config.two_stage=True`): + Predicted bounding boxes scores where the top `config.two_stage_num_proposals` scoring bounding boxes are + picked as region proposals in the first stage. Output of bounding box binary classification (i.e. + foreground and background). + enc_outputs_coord_logits (`torch.FloatTensor` of shape `(batch_size, sequence_length, 4)`, *optional*, returned when `config.with_box_refine=True` and `config.two_stage=True`): + Logits of predicted bounding boxes coordinates in the first stage. + denoising_meta_values (`dict`): + Extra dictionary for the denoising related values. + """ + + last_hidden_state: torch.FloatTensor | None = None + intermediate_hidden_states: torch.FloatTensor | None = None + intermediate_logits: torch.FloatTensor | None = None + intermediate_reference_points: torch.FloatTensor | None = None + intermediate_predicted_corners: torch.FloatTensor | None = None + initial_reference_points: torch.FloatTensor | None = None + decoder_hidden_states: tuple[torch.FloatTensor] | None = None + decoder_attentions: tuple[torch.FloatTensor] | None = None + cross_attentions: tuple[torch.FloatTensor] | None = None + encoder_last_hidden_state: torch.FloatTensor | None = None + encoder_hidden_states: tuple[torch.FloatTensor] | None = None + encoder_attentions: tuple[torch.FloatTensor] | None = None + init_reference_points: torch.FloatTensor | None = None + enc_topk_logits: torch.FloatTensor | None = None + enc_topk_bboxes: torch.FloatTensor | None = None + enc_outputs_class: torch.FloatTensor | None = None + enc_outputs_coord_logits: torch.FloatTensor | None = None + denoising_meta_values: dict | None = None + + +@dataclass +@auto_docstring( + custom_intro=""" + Output type of [`RTDetrForObjectDetection`]. + """ +) +class RTDetrObjectDetectionOutput(ModelOutput): + r""" + loss (`torch.FloatTensor` of shape `(1,)`, *optional*, returned when `labels` are provided)): + Total loss as a linear combination of a negative log-likehood (cross-entropy) for class prediction and a + bounding box loss. The latter is defined as a linear combination of the L1 loss and the generalized + scale-invariant IoU loss. + loss_dict (`Dict`, *optional*): + A dictionary containing the individual losses. Useful for logging. + logits (`torch.FloatTensor` of shape `(batch_size, num_queries, num_classes + 1)`): + Classification logits (including no-object) for all queries. + pred_boxes (`torch.FloatTensor` of shape `(batch_size, num_queries, 4)`): + Normalized boxes coordinates for all queries, represented as (center_x, center_y, width, height). These + values are normalized in [0, 1], relative to the size of each individual image in the batch (disregarding + possible padding). You can use [`~RTDetrImageProcessor.post_process_object_detection`] to retrieve the + unnormalized (absolute) bounding boxes. + auxiliary_outputs (`list[Dict]`, *optional*): + Optional, only returned when auxiliary losses are activated (i.e. `config.auxiliary_loss` is set to `True`) + and labels are provided. It is a list of dictionaries containing the two above keys (`logits` and + `pred_boxes`) for each decoder layer. + last_hidden_state (`torch.FloatTensor` of shape `(batch_size, num_queries, hidden_size)`): + Sequence of hidden-states at the output of the last layer of the decoder of the model. + intermediate_hidden_states (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, hidden_size)`): + Stacked intermediate hidden states (output of each layer of the decoder). + intermediate_logits (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, config.num_labels)`): + Stacked intermediate logits (logits of each layer of the decoder). + intermediate_reference_points (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, 4)`): + Stacked intermediate reference points (reference points of each layer of the decoder). + intermediate_predicted_corners (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, 4)`): + Stacked intermediate predicted corners (predicted corners of each layer of the decoder). + initial_reference_points (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, 4)`): + Stacked initial reference points (initial reference points of each layer of the decoder). + init_reference_points (`torch.FloatTensor` of shape `(batch_size, num_queries, 4)`): + Initial reference points sent through the Transformer decoder. + enc_topk_logits (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.num_labels)`, *optional*, returned when `config.with_box_refine=True` and `config.two_stage=True`): + Logits of predicted bounding boxes coordinates in the encoder. + enc_topk_bboxes (`torch.FloatTensor` of shape `(batch_size, sequence_length, 4)`, *optional*, returned when `config.with_box_refine=True` and `config.two_stage=True`): + Logits of predicted bounding boxes coordinates in the encoder. + enc_outputs_class (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.num_labels)`, *optional*, returned when `config.with_box_refine=True` and `config.two_stage=True`): + Predicted bounding boxes scores where the top `config.two_stage_num_proposals` scoring bounding boxes are + picked as region proposals in the first stage. Output of bounding box binary classification (i.e. + foreground and background). + enc_outputs_coord_logits (`torch.FloatTensor` of shape `(batch_size, sequence_length, 4)`, *optional*, returned when `config.with_box_refine=True` and `config.two_stage=True`): + Logits of predicted bounding boxes coordinates in the first stage. + denoising_meta_values (`dict`): + Extra dictionary for the denoising related values + """ + + loss: torch.FloatTensor | None = None + loss_dict: dict | None = None + logits: torch.FloatTensor | None = None + pred_boxes: torch.FloatTensor | None = None + auxiliary_outputs: list[dict] | None = None + last_hidden_state: torch.FloatTensor | None = None + intermediate_hidden_states: torch.FloatTensor | None = None + intermediate_logits: torch.FloatTensor | None = None + intermediate_reference_points: torch.FloatTensor | None = None + intermediate_predicted_corners: torch.FloatTensor | None = None + initial_reference_points: torch.FloatTensor | None = None + decoder_hidden_states: tuple[torch.FloatTensor] | None = None + decoder_attentions: tuple[torch.FloatTensor] | None = None + cross_attentions: tuple[torch.FloatTensor] | None = None + encoder_last_hidden_state: torch.FloatTensor | None = None + encoder_hidden_states: tuple[torch.FloatTensor] | None = None + encoder_attentions: tuple[torch.FloatTensor] | None = None + init_reference_points: tuple[torch.FloatTensor] | None = None + enc_topk_logits: torch.FloatTensor | None = None + enc_topk_bboxes: torch.FloatTensor | None = None + enc_outputs_class: torch.FloatTensor | None = None + enc_outputs_coord_logits: torch.FloatTensor | None = None + denoising_meta_values: dict | None = None + + +class RTDetrMLP(nn.Module): + def __init__(self, config: RTDetrConfig, hidden_size: int, intermediate_size: int, activation_function: str): + super().__init__() + self.fc1 = nn.Linear(hidden_size, intermediate_size) + self.fc2 = nn.Linear(intermediate_size, hidden_size) + self.activation_fn = ACT2FN[activation_function] + self.activation_dropout = config.activation_dropout + self.dropout = config.dropout + + def forward(self, hidden_states: torch.Tensor) -> torch.Tensor: + hidden_states = self.activation_fn(self.fc1(hidden_states)) + hidden_states = nn.functional.dropout(hidden_states, p=self.activation_dropout, training=self.training) + hidden_states = self.fc2(hidden_states) + hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training) + return hidden_states + + +class RTDetrFrozenBatchNorm2d(nn.Module): + """ + BatchNorm2d where the batch statistics and the affine parameters are fixed. + + Copy-paste from torchvision.misc.ops with added eps before rqsrt, without which any other models than + torchvision.models.resnet[18,34,50,101] produce nans. + """ + + def __init__(self, n): + super().__init__() + self.register_buffer("weight", torch.ones(n)) + self.register_buffer("bias", torch.zeros(n)) + self.register_buffer("running_mean", torch.zeros(n)) + self.register_buffer("running_var", torch.ones(n)) + + def _load_from_state_dict( + self, state_dict, prefix, local_metadata, strict, missing_keys, unexpected_keys, error_msgs + ): + num_batches_tracked_key = prefix + "num_batches_tracked" + if num_batches_tracked_key in state_dict: + del state_dict[num_batches_tracked_key] + + super()._load_from_state_dict( + state_dict, prefix, local_metadata, strict, missing_keys, unexpected_keys, error_msgs + ) + + def forward(self, x): + # move reshapes to the beginning + # to make it user-friendly + weight = self.weight.reshape(1, -1, 1, 1) + bias = self.bias.reshape(1, -1, 1, 1) + running_var = self.running_var.reshape(1, -1, 1, 1) + running_mean = self.running_mean.reshape(1, -1, 1, 1) + epsilon = 1e-5 + scale = weight * (running_var + epsilon).rsqrt() + bias = bias - running_mean * scale + return x * scale + bias + + +def eager_attention_forward( + module: nn.Module, + query: torch.Tensor, + key: torch.Tensor, + value: torch.Tensor, + attention_mask: torch.Tensor | None, + scaling: float | None = None, + dropout: float = 0.0, + **kwargs: Unpack[TransformersKwargs], +): + if scaling is None: + scaling = query.size(-1) ** -0.5 + + # Take the dot product between "query" and "key" to get the raw attention scores. + attn_weights = torch.matmul(query, key.transpose(2, 3)) * scaling + + if attention_mask is not None: + attn_weights = attn_weights + attention_mask + + attn_weights = nn.functional.softmax(attn_weights, dim=-1) + attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training) + + attn_output = torch.matmul(attn_weights, value) + attn_output = attn_output.transpose(1, 2).contiguous() + + return attn_output, attn_weights + + +class RTDetrSelfAttention(nn.Module): + """ + Multi-headed self-attention from 'Attention Is All You Need' paper. + + In RT_DETR, position embeddings are added to both queries and keys (but not values) in self-attention. + """ + + def __init__( + self, + config: RTDetrConfig, + hidden_size: int, + num_attention_heads: int, + dropout: float = 0.0, + bias: bool = True, + ): + super().__init__() + self.config = config + self.head_dim = hidden_size // num_attention_heads + self.scaling = self.head_dim**-0.5 + self.attention_dropout = dropout + self.is_causal = False + + self.k_proj = nn.Linear(hidden_size, hidden_size, bias=bias) + self.v_proj = nn.Linear(hidden_size, hidden_size, bias=bias) + self.q_proj = nn.Linear(hidden_size, hidden_size, bias=bias) + self.o_proj = nn.Linear(hidden_size, hidden_size, bias=bias) + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.Tensor | None = None, + position_embeddings: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor, torch.Tensor]: + """ + Position embeddings are added to both queries and keys (but not values). + """ + input_shape = hidden_states.shape[:-1] + hidden_shape = (*input_shape, -1, self.head_dim) + + query_key_input = hidden_states + position_embeddings if position_embeddings is not None else hidden_states + + query_states = self.q_proj(query_key_input).view(hidden_shape).transpose(1, 2) + key_states = self.k_proj(query_key_input).view(hidden_shape).transpose(1, 2) + value_states = self.v_proj(hidden_states).view(hidden_shape).transpose(1, 2) + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, eager_attention_forward + ) + + attn_output, attn_weights = attention_interface( + self, + query_states, + key_states, + value_states, + attention_mask, + dropout=0.0 if not self.training else self.attention_dropout, + scaling=self.scaling, + **kwargs, + ) + + attn_output = attn_output.reshape(*input_shape, -1).contiguous() + attn_output = self.o_proj(attn_output) + return attn_output, attn_weights + + +def replace_batch_norm(model): + r""" + Recursively replace all `torch.nn.BatchNorm2d` with `RTDetrFrozenBatchNorm2d`. + + Args: + model (torch.nn.Module): + input model + """ + for name, module in model.named_children(): + if isinstance(module, nn.BatchNorm2d): + new_module = RTDetrFrozenBatchNorm2d(module.num_features) + + if module.weight.device != torch.device("meta"): + new_module.weight.copy_(module.weight) + new_module.bias.copy_(module.bias) + new_module.running_mean.copy_(module.running_mean) + new_module.running_var.copy_(module.running_var) + + model._modules[name] = new_module + + if len(list(module.children())) > 0: + replace_batch_norm(module) + + +class RTDetrConvEncoder(nn.Module): + """ + Convolutional backbone using the modeling_rt_detr_resnet.py. + + nn.BatchNorm2d layers are replaced by RTDetrFrozenBatchNorm2d as defined above. + https://github.com/lyuwenyu/RT-DETR/blob/main/rtdetr_pytorch/src/nn/backbone/presnet.py#L142 + """ + + def __init__(self, config): + super().__init__() + + backbone = load_backbone(config) + + if config.freeze_backbone_batch_norms: + # replace batch norm by frozen batch norm + with torch.no_grad(): + replace_batch_norm(backbone) + self.model = backbone + self.intermediate_channel_sizes = self.model.channels + + def forward(self, pixel_values: torch.Tensor, pixel_mask: torch.Tensor): + # send pixel_values through the model to get list of feature maps + features = self.model(pixel_values).feature_maps + + out = [] + for feature_map in features: + # downsample pixel_mask to match shape of corresponding feature_map + mask = nn.functional.interpolate(pixel_mask[None].float(), size=feature_map.shape[-2:]).to(torch.bool)[0] + out.append((feature_map, mask)) + return out + + +class RTDetrConvNormLayer(nn.Module): + def __init__(self, config, in_channels, out_channels, kernel_size, stride, padding=None, activation=None): + super().__init__() + self.conv = nn.Conv2d( + in_channels, + out_channels, + kernel_size, + stride, + padding=(kernel_size - 1) // 2 if padding is None else padding, + bias=False, + ) + self.norm = nn.BatchNorm2d(out_channels, config.batch_norm_eps) + self.activation = nn.Identity() if activation is None else ACT2CLS[activation]() + + def forward(self, hidden_state): + hidden_state = self.conv(hidden_state) + hidden_state = self.norm(hidden_state) + hidden_state = self.activation(hidden_state) + return hidden_state + + +class RTDetrEncoderLayer(nn.Module): + def __init__(self, config: RTDetrConfig): + super().__init__() + self.normalize_before = config.normalize_before + self.hidden_size = config.encoder_hidden_dim + + # self-attention + self.self_attn = RTDetrSelfAttention( + config=config, + hidden_size=self.hidden_size, + num_attention_heads=config.num_attention_heads, + dropout=config.dropout, + ) + self.self_attn_layer_norm = nn.LayerNorm(self.hidden_size, eps=config.layer_norm_eps) + self.dropout = config.dropout + self.mlp = RTDetrMLP(config, self.hidden_size, config.encoder_ffn_dim, config.encoder_activation_function) + self.final_layer_norm = nn.LayerNorm(self.hidden_size, eps=config.layer_norm_eps) + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.Tensor, + spatial_position_embeddings: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> torch.Tensor: + """ + Args: + hidden_states (`torch.FloatTensor`): input to the layer of shape `(batch, seq_len, hidden_size)` + attention_mask (`torch.FloatTensor`): attention mask of size + `(batch, 1, target_len, source_len)` where padding elements are indicated by very large negative + values. + spatial_position_embeddings (`torch.FloatTensor`, *optional*): + Spatial position embeddings (2D positional encodings of image locations), to be added to both + the queries and keys in self-attention (but not to values). + """ + residual = hidden_states + if self.normalize_before: + hidden_states = self.self_attn_layer_norm(hidden_states) + + hidden_states, _ = self.self_attn( + hidden_states=hidden_states, + attention_mask=attention_mask, + position_embeddings=spatial_position_embeddings, + **kwargs, + ) + + hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training) + hidden_states = residual + hidden_states + if not self.normalize_before: + hidden_states = self.self_attn_layer_norm(hidden_states) + + if self.normalize_before: + hidden_states = self.final_layer_norm(hidden_states) + residual = hidden_states + + hidden_states = self.mlp(hidden_states) + + hidden_states = residual + hidden_states + if not self.normalize_before: + hidden_states = self.final_layer_norm(hidden_states) + + if self.training: + if not torch.isfinite(hidden_states).all(): + clamp_value = torch.finfo(hidden_states.dtype).max - 1000 + hidden_states = torch.clamp(hidden_states, min=-clamp_value, max=clamp_value) + + return hidden_states + + +class RTDetrRepVggBlock(nn.Module): + """ + RepVGG architecture block introduced by the work "RepVGG: Making VGG-style ConvNets Great Again". + """ + + def __init__(self, config: RTDetrConfig): + super().__init__() + + activation = config.activation_function + hidden_channels = int(config.encoder_hidden_dim * config.hidden_expansion) + self.conv1 = RTDetrConvNormLayer(config, hidden_channels, hidden_channels, 3, 1, padding=1) + self.conv2 = RTDetrConvNormLayer(config, hidden_channels, hidden_channels, 1, 1, padding=0) + self.activation = nn.Identity() if activation is None else ACT2CLS[activation]() + + def forward(self, x): + y = self.conv1(x) + self.conv2(x) + return self.activation(y) + + +class RTDetrCSPRepLayer(nn.Module): + """ + Cross Stage Partial (CSP) network layer with RepVGG blocks. + """ + + def __init__(self, config: RTDetrConfig): + super().__init__() + + in_channels = config.encoder_hidden_dim * 2 + out_channels = config.encoder_hidden_dim + num_blocks = 3 + activation = config.activation_function + + hidden_channels = int(out_channels * config.hidden_expansion) + self.conv1 = RTDetrConvNormLayer(config, in_channels, hidden_channels, 1, 1, activation=activation) + self.conv2 = RTDetrConvNormLayer(config, in_channels, hidden_channels, 1, 1, activation=activation) + self.bottlenecks = nn.Sequential(*[RTDetrRepVggBlock(config) for _ in range(num_blocks)]) + if hidden_channels != out_channels: + self.conv3 = RTDetrConvNormLayer(config, hidden_channels, out_channels, 1, 1, activation=activation) + else: + self.conv3 = nn.Identity() + + def forward(self, hidden_state): + hidden_state_1 = self.conv1(hidden_state) + hidden_state_1 = self.bottlenecks(hidden_state_1) + hidden_state_2 = self.conv2(hidden_state) + return self.conv3(hidden_state_1 + hidden_state_2) + + +@use_kernel_forward_from_hub("MultiScaleDeformableAttention") +class MultiScaleDeformableAttention(nn.Module): + def forward( + self, + value: Tensor, + value_spatial_shapes: Tensor, + value_spatial_shapes_list: list[tuple], + level_start_index: Tensor, + sampling_locations: Tensor, + attention_weights: Tensor, + im2col_step: int, + ): + batch_size, _, num_heads, hidden_dim = value.shape + _, num_queries, num_heads, num_levels, num_points, _ = sampling_locations.shape + value_list = value.split([height * width for height, width in value_spatial_shapes_list], dim=1) + sampling_grids = 2 * sampling_locations - 1 + sampling_value_list = [] + for level_id, (height, width) in enumerate(value_spatial_shapes_list): + # batch_size, height*width, num_heads, hidden_dim + # -> batch_size, height*width, num_heads*hidden_dim + # -> batch_size, num_heads*hidden_dim, height*width + # -> batch_size*num_heads, hidden_dim, height, width + value_l_ = ( + value_list[level_id] + .flatten(2) + .transpose(1, 2) + .reshape(batch_size * num_heads, hidden_dim, height, width) + ) + # batch_size, num_queries, num_heads, num_points, 2 + # -> batch_size, num_heads, num_queries, num_points, 2 + # -> batch_size*num_heads, num_queries, num_points, 2 + sampling_grid_l_ = sampling_grids[:, :, :, level_id].transpose(1, 2).flatten(0, 1) + # batch_size*num_heads, hidden_dim, num_queries, num_points + sampling_value_l_ = nn.functional.grid_sample( + value_l_, + sampling_grid_l_, + mode="bilinear", + padding_mode="zeros", + align_corners=False, + ) + sampling_value_list.append(sampling_value_l_) + # (batch_size, num_queries, num_heads, num_levels, num_points) + # -> (batch_size, num_heads, num_queries, num_levels, num_points) + # -> (batch_size, num_heads, 1, num_queries, num_levels*num_points) + attention_weights = attention_weights.transpose(1, 2).reshape( + batch_size * num_heads, 1, num_queries, num_levels * num_points + ) + output = ( + (torch.stack(sampling_value_list, dim=-2).flatten(-2) * attention_weights) + .sum(-1) + .view(batch_size, num_heads * hidden_dim, num_queries) + ) + return output.transpose(1, 2).contiguous() + + +class RTDetrMultiscaleDeformableAttention(nn.Module): + """ + Multiscale deformable attention as proposed in Deformable DETR. + """ + + def __init__(self, config: RTDetrConfig, num_heads: int, n_points: int): + super().__init__() + + self.attn = MultiScaleDeformableAttention() + + if config.d_model % num_heads != 0: + raise ValueError( + f"embed_dim (d_model) must be divisible by num_heads, but got {config.d_model} and {num_heads}" + ) + dim_per_head = config.d_model // num_heads + # check if dim_per_head is power of 2 + if not ((dim_per_head & (dim_per_head - 1) == 0) and dim_per_head != 0): + warnings.warn( + "You'd better set embed_dim (d_model) in RTDetrMultiscaleDeformableAttention to make the" + " dimension of each attention head a power of 2 which is more efficient in the authors' CUDA" + " implementation." + ) + + self.im2col_step = 64 + + self.d_model = config.d_model + self.n_levels = config.num_feature_levels + self.n_heads = num_heads + self.n_points = n_points + + self.sampling_offsets = nn.Linear(config.d_model, num_heads * self.n_levels * n_points * 2) + self.attention_weights = nn.Linear(config.d_model, num_heads * self.n_levels * n_points) + self.value_proj = nn.Linear(config.d_model, config.d_model) + self.output_proj = nn.Linear(config.d_model, config.d_model) + + self.disable_custom_kernels = config.disable_custom_kernels + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.Tensor | None = None, + encoder_hidden_states=None, + encoder_attention_mask=None, + position_embeddings: torch.Tensor | None = None, + reference_points=None, + spatial_shapes=None, + spatial_shapes_list=None, + level_start_index=None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor, torch.Tensor]: + # add position embeddings to the hidden states before projecting to queries and keys + if position_embeddings is not None: + hidden_states = hidden_states + position_embeddings + + batch_size, num_queries, _ = hidden_states.shape + batch_size, sequence_length, _ = encoder_hidden_states.shape + total_elements = sum(height * width for height, width in spatial_shapes_list) + torch_compilable_check( + total_elements == sequence_length, + "Make sure to align the spatial shapes with the sequence length of the encoder hidden states", + ) + + value = self.value_proj(encoder_hidden_states) + if attention_mask is not None: + # we invert the attention_mask + value = value.masked_fill(~attention_mask[..., None], float(0)) + value = value.view(batch_size, sequence_length, self.n_heads, self.d_model // self.n_heads) + sampling_offsets = self.sampling_offsets(hidden_states).view( + batch_size, num_queries, self.n_heads, self.n_levels, self.n_points, 2 + ) + attention_weights = self.attention_weights(hidden_states).view( + batch_size, num_queries, self.n_heads, self.n_levels * self.n_points + ) + attention_weights = F.softmax(attention_weights, -1).view( + batch_size, num_queries, self.n_heads, self.n_levels, self.n_points + ) + # batch_size, num_queries, n_heads, n_levels, n_points, 2 + num_coordinates = reference_points.shape[-1] + if num_coordinates == 2: + offset_normalizer = torch.stack([spatial_shapes[..., 1], spatial_shapes[..., 0]], -1) + sampling_locations = ( + reference_points[:, :, None, :, None, :] + + sampling_offsets / offset_normalizer[None, None, None, :, None, :] + ) + elif num_coordinates == 4: + sampling_locations = ( + reference_points[:, :, None, :, None, :2] + + sampling_offsets / self.n_points * reference_points[:, :, None, :, None, 2:] * 0.5 + ) + else: + raise ValueError(f"Last dim of reference_points must be 2 or 4, but got {reference_points.shape[-1]}") + + output = self.attn( + value, + spatial_shapes, + spatial_shapes_list, + level_start_index, + sampling_locations, + attention_weights, + self.im2col_step, + ) + + output = self.output_proj(output) + + return output, attention_weights + + +class RTDetrDecoderLayer(nn.Module): + def __init__(self, config: RTDetrConfig): + super().__init__() + self.hidden_size = config.d_model + + # self-attention + self.self_attn = RTDetrSelfAttention( + config=config, + hidden_size=self.hidden_size, + num_attention_heads=config.decoder_attention_heads, + dropout=config.attention_dropout, + ) + self.dropout = config.dropout + + self.self_attn_layer_norm = nn.LayerNorm(self.hidden_size, eps=config.layer_norm_eps) + # cross-attention + self.encoder_attn = RTDetrMultiscaleDeformableAttention( + config, + num_heads=config.decoder_attention_heads, + n_points=config.decoder_n_points, + ) + self.encoder_attn_layer_norm = nn.LayerNorm(self.hidden_size, eps=config.layer_norm_eps) + # feedforward neural networks + self.mlp = RTDetrMLP(config, self.hidden_size, config.decoder_ffn_dim, config.decoder_activation_function) + self.final_layer_norm = nn.LayerNorm(self.hidden_size, eps=config.layer_norm_eps) + + def forward( + self, + hidden_states: torch.Tensor, + object_queries_position_embeddings: torch.Tensor | None = None, + reference_points=None, + spatial_shapes=None, + spatial_shapes_list=None, + level_start_index=None, + encoder_hidden_states: torch.Tensor | None = None, + encoder_attention_mask: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> torch.Tensor: + """ + Args: + hidden_states (`torch.FloatTensor`): + Input to the layer of shape `(batch, seq_len, hidden_size)`. + object_queries_position_embeddings (`torch.FloatTensor`, *optional*): + Position embeddings for the object query slots. These are added to both queries and keys + in the self-attention layer (not values). + reference_points (`torch.FloatTensor`, *optional*): + Reference points. + spatial_shapes (`torch.LongTensor`, *optional*): + Spatial shapes. + level_start_index (`torch.LongTensor`, *optional*): + Level start index. + encoder_hidden_states (`torch.FloatTensor`): + cross attention input to the layer of shape `(batch, seq_len, hidden_size)` + encoder_attention_mask (`torch.FloatTensor`): encoder attention mask of size + `(batch, 1, target_len, source_len)` where padding elements are indicated by very large negative + values. + """ + residual = hidden_states + + # Self Attention + hidden_states, _ = self.self_attn( + hidden_states=hidden_states, + attention_mask=encoder_attention_mask, + position_embeddings=object_queries_position_embeddings, + **kwargs, + ) + + hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training) + hidden_states = residual + hidden_states + hidden_states = self.self_attn_layer_norm(hidden_states) + + residual = hidden_states + + # Cross-Attention + hidden_states, _ = self.encoder_attn( + hidden_states=hidden_states, + encoder_hidden_states=encoder_hidden_states, + position_embeddings=object_queries_position_embeddings, + reference_points=reference_points, + spatial_shapes=spatial_shapes, + spatial_shapes_list=spatial_shapes_list, + level_start_index=level_start_index, + **kwargs, + ) + + hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training) + hidden_states = residual + hidden_states + + hidden_states = self.encoder_attn_layer_norm(hidden_states) + + # Fully Connected + residual = hidden_states + hidden_states = self.mlp(hidden_states) + hidden_states = residual + hidden_states + hidden_states = self.final_layer_norm(hidden_states) + + return hidden_states + + +class RTDetrSinePositionEmbedding(nn.Module): + """ + 2D sinusoidal position embedding used in RT-DETR hybrid encoder. + """ + + def __init__(self, embed_dim: int = 256, temperature: int = 10000): + super().__init__() + self.embed_dim = embed_dim + self.temperature = temperature + + @compile_compatible_method_lru_cache(maxsize=32) + def forward( + self, + width: int, + height: int, + device: torch.device | str, + dtype: torch.dtype, + ) -> torch.Tensor: + """ + Generate 2D sinusoidal position embeddings. + + Returns: + Position embeddings of shape (1, height*width, embed_dim) + """ + grid_w = torch.arange(torch_int(width), device=device).to(dtype) + grid_h = torch.arange(torch_int(height), device=device).to(dtype) + grid_w, grid_h = torch.meshgrid(grid_w, grid_h, indexing="xy") + if self.embed_dim % 4 != 0: + raise ValueError("Embed dimension must be divisible by 4 for 2D sin-cos position embedding") + pos_dim = self.embed_dim // 4 + omega = torch.arange(pos_dim, device=device).to(dtype) / pos_dim + omega = 1.0 / (self.temperature**omega) + + out_w = grid_w.flatten()[..., None] @ omega[None] + out_h = grid_h.flatten()[..., None] @ omega[None] + + return torch.concat([out_h.sin(), out_h.cos(), out_w.sin(), out_w.cos()], dim=1)[None, :, :] + + +class RTDetrAIFILayer(nn.Module): + """ + AIFI (Attention-based Intra-scale Feature Interaction) layer used in RT-DETR hybrid encoder. + """ + + def __init__(self, config: RTDetrConfig): + super().__init__() + self.config = config + self.encoder_hidden_dim = config.encoder_hidden_dim + self.eval_size = config.eval_size + + self.position_embedding = RTDetrSinePositionEmbedding( + embed_dim=self.encoder_hidden_dim, + temperature=config.positional_encoding_temperature, + ) + self.layers = nn.ModuleList([RTDetrEncoderLayer(config) for _ in range(config.encoder_layers)]) + + def forward( + self, + hidden_states: torch.Tensor, + **kwargs: Unpack[TransformersKwargs], + ) -> torch.Tensor: + """ + Args: + hidden_states (`torch.FloatTensor` of shape `(batch_size, channels, height, width)`): + Feature map to process. + """ + batch_size = hidden_states.shape[0] + height, width = hidden_states.shape[2:] + + hidden_states = hidden_states.flatten(2).permute(0, 2, 1) + + if self.training or self.eval_size is None: + pos_embed = self.position_embedding( + width=width, + height=height, + device=hidden_states.device, + dtype=hidden_states.dtype, + ) + else: + pos_embed = None + + for layer in self.layers: + hidden_states = layer( + hidden_states, + attention_mask=None, + spatial_position_embeddings=pos_embed, + **kwargs, + ) + + hidden_states = ( + hidden_states.permute(0, 2, 1).reshape(batch_size, self.encoder_hidden_dim, height, width).contiguous() + ) + + return hidden_states + + +class RTDetrMLPPredictionHead(nn.Module): + """ + Very simple multi-layer perceptron (MLP, also called FFN), used to predict the normalized center coordinates, + height and width of a bounding box w.r.t. an image. + + """ + + def __init__(self, input_dim, hidden_dim, output_dim, num_layers): + super().__init__() + self.num_layers = num_layers + h = [hidden_dim] * (num_layers - 1) + self.layers = nn.ModuleList(nn.Linear(n, k) for n, k in zip([input_dim] + h, h + [output_dim])) + + def forward(self, x): + for i, layer in enumerate(self.layers): + x = nn.functional.relu(layer(x)) if i < self.num_layers - 1 else layer(x) + return x + + +@auto_docstring +class RTDetrPreTrainedModel(PreTrainedModel): + config: RTDetrConfig + base_model_prefix = "rt_detr" + main_input_name = "pixel_values" + input_modalities = ("image",) + _no_split_modules = [r"RTDetrHybridEncoder", r"RTDetrDecoderLayer"] + _supports_sdpa = True + _supports_flash_attn = True + _supports_attention_backend = True + _supports_flex_attn = True + + @torch.no_grad() + def _init_weights(self, module): + """Initialize the weights""" + if isinstance(module, RTDetrForObjectDetection): + if module.model.decoder.class_embed is not None: + for layer in module.model.decoder.class_embed: + prior_prob = self.config.initializer_bias_prior_prob or 1 / (self.config.num_labels + 1) + bias = float(-math.log((1 - prior_prob) / prior_prob)) + init.xavier_uniform_(layer.weight) + init.constant_(layer.bias, bias) + + if module.model.decoder.bbox_embed is not None: + for layer in module.model.decoder.bbox_embed: + init.constant_(layer.layers[-1].weight, 0) + init.constant_(layer.layers[-1].bias, 0) + + elif isinstance(module, RTDetrMultiscaleDeformableAttention): + init.constant_(module.sampling_offsets.weight, 0.0) + default_dtype = torch.get_default_dtype() + thetas = torch.arange(module.n_heads, dtype=torch.int64).to(default_dtype) * ( + 2.0 * math.pi / module.n_heads + ) + grid_init = torch.stack([thetas.cos(), thetas.sin()], -1) + grid_init = ( + (grid_init / grid_init.abs().max(-1, keepdim=True)[0]) + .view(module.n_heads, 1, 1, 2) + .repeat(1, module.n_levels, module.n_points, 1) + ) + for i in range(module.n_points): + grid_init[:, :, i, :] *= i + 1 + + init.copy_(module.sampling_offsets.bias, grid_init.view(-1)) + init.constant_(module.attention_weights.weight, 0.0) + init.constant_(module.attention_weights.bias, 0.0) + init.xavier_uniform_(module.value_proj.weight) + init.constant_(module.value_proj.bias, 0.0) + init.xavier_uniform_(module.output_proj.weight) + init.constant_(module.output_proj.bias, 0.0) + + elif isinstance(module, RTDetrModel): + prior_prob = self.config.initializer_bias_prior_prob or 1 / (self.config.num_labels + 1) + bias = float(-math.log((1 - prior_prob) / prior_prob)) + init.xavier_uniform_(module.enc_score_head.weight) + init.constant_(module.enc_score_head.bias, bias) + + elif isinstance(module, (nn.Linear, nn.Conv2d, nn.BatchNorm2d)): + init.normal_(module.weight, mean=0.0, std=self.config.initializer_range) + if module.bias is not None: + init.zeros_(module.bias) + if getattr(module, "running_mean", None) is not None: + init.zeros_(module.running_mean) + init.ones_(module.running_var) + init.zeros_(module.num_batches_tracked) + + elif isinstance(module, nn.LayerNorm): + init.ones_(module.weight) + init.zeros_(module.bias) + + if hasattr(module, "weight_embedding") and self.config.learn_initial_query: + init.xavier_uniform_(module.weight_embedding.weight) + if hasattr(module, "denoising_class_embed") and self.config.num_denoising > 0: + init.xavier_uniform_(module.denoising_class_embed.weight) + + +class RTDetrHybridEncoder(RTDetrPreTrainedModel): + """ + Hybrid encoder consisting of AIFI (Attention-based Intra-scale Feature Interaction) layers, + a top-down Feature Pyramid Network (FPN) and a bottom-up Path Aggregation Network (PAN). + More details on the paper: https://huggingface.co/papers/2304.08069 + + Args: + config: RTDetrConfig + """ + + _can_record_outputs = { + "hidden_states": RTDetrAIFILayer, + "attentions": RTDetrSelfAttention, + } + + def __init__(self, config: RTDetrConfig): + super().__init__(config) + self.config = config + self.in_channels = config.encoder_in_channels + self.feat_strides = config.feat_strides + self.encoder_hidden_dim = config.encoder_hidden_dim + self.encode_proj_layers = config.encode_proj_layers + self.positional_encoding_temperature = config.positional_encoding_temperature + self.eval_size = config.eval_size + self.out_channels = [self.encoder_hidden_dim for _ in self.in_channels] + self.out_strides = self.feat_strides + self.num_fpn_stages = len(self.in_channels) - 1 + self.num_pan_stages = len(self.in_channels) - 1 + + # AIFI (Attention-based Intra-scale Feature Interaction) layers + self.aifi = nn.ModuleList([RTDetrAIFILayer(config) for _ in range(len(self.encode_proj_layers))]) + + # top-down FPN + self.lateral_convs = nn.ModuleList() + self.fpn_blocks = nn.ModuleList() + for _ in range(self.num_fpn_stages): + lateral_conv = RTDetrConvNormLayer( + config, + in_channels=self.encoder_hidden_dim, + out_channels=self.encoder_hidden_dim, + kernel_size=1, + stride=1, + activation=config.activation_function, + ) + fpn_block = RTDetrCSPRepLayer(config) + self.lateral_convs.append(lateral_conv) + self.fpn_blocks.append(fpn_block) + + # bottom-up PAN + self.downsample_convs = nn.ModuleList() + self.pan_blocks = nn.ModuleList() + for _ in range(self.num_pan_stages): + downsample_conv = RTDetrConvNormLayer( + config, + in_channels=self.encoder_hidden_dim, + out_channels=self.encoder_hidden_dim, + kernel_size=3, + stride=2, + activation=config.activation_function, + ) + pan_block = RTDetrCSPRepLayer(config) + self.downsample_convs.append(downsample_conv) + self.pan_blocks.append(pan_block) + + self.post_init() + + @merge_with_config_defaults + @capture_outputs(tie_last_hidden_states=False) + def forward( + self, + inputs_embeds=None, + **kwargs: Unpack[TransformersKwargs], + ) -> BaseModelOutput: + r""" + Args: + inputs_embeds (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`): + Flattened feature map (output of the backbone + projection layer) that is passed to the encoder. + """ + feature_maps = inputs_embeds + + # AIFI: Apply transformer encoder to specified feature levels + if self.config.encoder_layers > 0: + for i, enc_ind in enumerate(self.encode_proj_layers): + feature_maps[enc_ind] = self.aifi[i](feature_maps[enc_ind], **kwargs) + + # top-down FPN + fpn_feature_maps = [feature_maps[-1]] + for idx, (lateral_conv, fpn_block) in enumerate(zip(self.lateral_convs, self.fpn_blocks)): + backbone_feature_map = feature_maps[self.num_fpn_stages - idx - 1] + top_fpn_feature_map = fpn_feature_maps[-1] + # apply lateral block + top_fpn_feature_map = lateral_conv(top_fpn_feature_map) + fpn_feature_maps[-1] = top_fpn_feature_map + # apply fpn block + top_fpn_feature_map = F.interpolate(top_fpn_feature_map, scale_factor=2.0, mode="nearest") + fused_feature_map = torch.concat([top_fpn_feature_map, backbone_feature_map], dim=1) + new_fpn_feature_map = fpn_block(fused_feature_map) + fpn_feature_maps.append(new_fpn_feature_map) + + fpn_feature_maps.reverse() + + # bottom-up PAN + pan_feature_maps = [fpn_feature_maps[0]] + for idx, (downsample_conv, pan_block) in enumerate(zip(self.downsample_convs, self.pan_blocks)): + top_pan_feature_map = pan_feature_maps[-1] + fpn_feature_map = fpn_feature_maps[idx + 1] + downsampled_feature_map = downsample_conv(top_pan_feature_map) + fused_feature_map = torch.concat([downsampled_feature_map, fpn_feature_map], dim=1) + new_pan_feature_map = pan_block(fused_feature_map) + pan_feature_maps.append(new_pan_feature_map) + + return BaseModelOutput(last_hidden_state=pan_feature_maps) + + +def inverse_sigmoid(x, eps=1e-5): + x = x.clamp(min=0, max=1) + x1 = x.clamp(min=eps) + x2 = (1 - x).clamp(min=eps) + return torch.log(x1 / x2) + + +class RTDetrDecoder(RTDetrPreTrainedModel): + _can_record_outputs = { + "hidden_states": RTDetrDecoderLayer, + "attentions": RTDetrSelfAttention, + "cross_attentions": RTDetrMultiscaleDeformableAttention, + } + + def __init__(self, config: RTDetrConfig): + super().__init__(config) + + self.dropout = config.dropout + self.layers = nn.ModuleList([RTDetrDecoderLayer(config) for _ in range(config.decoder_layers)]) + self.query_pos_head = RTDetrMLPPredictionHead(4, 2 * config.d_model, config.d_model, num_layers=2) + + # hack implementation for iterative bounding box refinement and two-stage Deformable DETR + self.bbox_embed = None + self.class_embed = None + + # Initialize weights and apply final processing + self.post_init() + + @merge_with_config_defaults + @capture_outputs + def forward( + self, + inputs_embeds=None, + encoder_hidden_states=None, + encoder_attention_mask=None, + reference_points=None, + spatial_shapes=None, + spatial_shapes_list=None, + level_start_index=None, + **kwargs: Unpack[TransformersKwargs], + ): + r""" + Args: + inputs_embeds (`torch.FloatTensor` of shape `(batch_size, num_queries, hidden_size)`): + The query embeddings that are passed into the decoder. + encoder_hidden_states (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*): + Sequence of hidden-states at the output of the last layer of the encoder. Used in the cross-attention + of the decoder. + encoder_attention_mask (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Mask to avoid performing cross-attention on padding pixel_values of the encoder. Mask values selected + in `[0, 1]`: + - 1 for pixels that are real (i.e. **not masked**), + - 0 for pixels that are padding (i.e. **masked**). + reference_points (`torch.FloatTensor` of shape `(batch_size, num_queries, 4)` is `as_two_stage` else `(batch_size, num_queries, 2)` or , *optional*): + Reference point in range `[0, 1]`, top-left (0,0), bottom-right (1, 1), including padding area. + spatial_shapes (`torch.FloatTensor` of shape `(num_feature_levels, 2)`): + Spatial shapes of the feature maps. + level_start_index (`torch.LongTensor` of shape `(num_feature_levels)`, *optional*): + Indexes for the start of each feature level. In range `[0, sequence_length]`. + """ + if inputs_embeds is not None: + hidden_states = inputs_embeds + + # decoder layers + intermediate = () + intermediate_reference_points = () + intermediate_logits = () + + reference_points = F.sigmoid(reference_points) + + # https://github.com/lyuwenyu/RT-DETR/blob/94f5e16708329d2f2716426868ec89aa774af016/rtdetr_pytorch/src/zoo/rtdetr/rtdetr_decoder.py#L252 + for idx, decoder_layer in enumerate(self.layers): + reference_points_input = reference_points.unsqueeze(2) + object_queries_position_embeddings = self.query_pos_head(reference_points) + + hidden_states = decoder_layer( + hidden_states, + object_queries_position_embeddings=object_queries_position_embeddings, + encoder_hidden_states=encoder_hidden_states, + reference_points=reference_points_input, + spatial_shapes=spatial_shapes, + spatial_shapes_list=spatial_shapes_list, + level_start_index=level_start_index, + encoder_attention_mask=encoder_attention_mask, + **kwargs, + ) + + # hack implementation for iterative bounding box refinement + if self.bbox_embed is not None: + predicted_corners = self.bbox_embed[idx](hidden_states) + new_reference_points = F.sigmoid(predicted_corners + inverse_sigmoid(reference_points)) + reference_points = new_reference_points.detach() + + intermediate += (hidden_states,) + intermediate_reference_points += ( + (new_reference_points,) if self.bbox_embed is not None else (reference_points,) + ) + + if self.class_embed is not None: + logits = self.class_embed[idx](hidden_states) + intermediate_logits += (logits,) + + # Keep batch_size as first dimension + intermediate = torch.stack(intermediate, dim=1) + intermediate_reference_points = torch.stack(intermediate_reference_points, dim=1) + if self.class_embed is not None: + intermediate_logits = torch.stack(intermediate_logits, dim=1) + + return RTDetrDecoderOutput( + last_hidden_state=hidden_states, + intermediate_hidden_states=intermediate, + intermediate_logits=intermediate_logits, + intermediate_reference_points=intermediate_reference_points, + ) + + +def get_contrastive_denoising_training_group( + targets, + num_classes, + num_queries, + class_embed, + num_denoising_queries=100, + label_noise_ratio=0.5, + box_noise_scale=1.0, +): + """ + Creates a contrastive denoising training group using ground-truth samples. It adds noise to labels and boxes. + + Args: + targets (`list[dict]`): + The target objects, each containing 'class_labels' and 'boxes' for objects in an image. + num_classes (`int`): + Total number of classes in the dataset. + num_queries (`int`): + Number of query slots in the transformer. + class_embed (`callable`): + A function or a model layer to embed class labels. + num_denoising_queries (`int`, *optional*, defaults to 100): + Number of denoising queries. + label_noise_ratio (`float`, *optional*, defaults to 0.5): + Ratio of noise applied to labels. + box_noise_scale (`float`, *optional*, defaults to 1.0): + Scale of noise applied to bounding boxes. + Returns: + `tuple` comprising various elements: + - **input_query_class** (`torch.FloatTensor`) -- + Class queries with applied label noise. + - **input_query_bbox** (`torch.FloatTensor`) -- + Bounding box queries with applied box noise. + - **attn_mask** (`torch.FloatTensor`) -- + Attention mask for separating denoising and reconstruction queries. + - **denoising_meta_values** (`dict`) -- + Metadata including denoising positive indices, number of groups, and split sizes. + """ + + if num_denoising_queries <= 0: + return None, None, None, None + + num_ground_truths = [len(t["class_labels"]) for t in targets] + device = targets[0]["class_labels"].device + + max_gt_num = max(num_ground_truths) + if max_gt_num == 0: + return None, None, None, None + + num_groups_denoising_queries = num_denoising_queries // max_gt_num + num_groups_denoising_queries = 1 if num_groups_denoising_queries == 0 else num_groups_denoising_queries + # pad gt to max_num of a batch + batch_size = len(num_ground_truths) + + input_query_class = torch.full([batch_size, max_gt_num], num_classes, dtype=torch.int32, device=device) + input_query_bbox = torch.zeros([batch_size, max_gt_num, 4], device=device) + pad_gt_mask = torch.zeros([batch_size, max_gt_num], dtype=torch.bool, device=device) + + for i in range(batch_size): + num_gt = num_ground_truths[i] + if num_gt > 0: + input_query_class[i, :num_gt] = targets[i]["class_labels"] + input_query_bbox[i, :num_gt] = targets[i]["boxes"] + pad_gt_mask[i, :num_gt] = 1 + # each group has positive and negative queries. + input_query_class = input_query_class.tile([1, 2 * num_groups_denoising_queries]) + input_query_bbox = input_query_bbox.tile([1, 2 * num_groups_denoising_queries, 1]) + pad_gt_mask = pad_gt_mask.tile([1, 2 * num_groups_denoising_queries]) + # positive and negative mask + negative_gt_mask = torch.zeros([batch_size, max_gt_num * 2, 1], device=device) + negative_gt_mask[:, max_gt_num:] = 1 + negative_gt_mask = negative_gt_mask.tile([1, num_groups_denoising_queries, 1]) + positive_gt_mask = 1 - negative_gt_mask + # contrastive denoising training positive index + positive_gt_mask = positive_gt_mask.squeeze(-1) * pad_gt_mask + denoise_positive_idx = torch.nonzero(positive_gt_mask)[:, 1] + denoise_positive_idx = torch.split( + denoise_positive_idx, [n * num_groups_denoising_queries for n in num_ground_truths] + ) + # total denoising queries + num_denoising_queries = torch_int(max_gt_num * 2 * num_groups_denoising_queries) + + if label_noise_ratio > 0: + mask = torch.rand_like(input_query_class, dtype=torch.float) < (label_noise_ratio * 0.5) + # randomly put a new one here + new_label = torch.randint_like(mask, 0, num_classes, dtype=input_query_class.dtype) + input_query_class = torch.where(mask & pad_gt_mask, new_label, input_query_class) + + if box_noise_scale > 0: + known_bbox = center_to_corners_format(input_query_bbox) + diff = torch.tile(input_query_bbox[..., 2:] * 0.5, [1, 1, 2]) * box_noise_scale + rand_sign = torch.randint_like(input_query_bbox, 0, 2) * 2.0 - 1.0 + rand_part = torch.rand_like(input_query_bbox) + rand_part = (rand_part + 1.0) * negative_gt_mask + rand_part * (1 - negative_gt_mask) + rand_part *= rand_sign + known_bbox += rand_part * diff + known_bbox.clip_(min=0.0, max=1.0) + input_query_bbox = corners_to_center_format(known_bbox) + input_query_bbox = inverse_sigmoid(input_query_bbox) + + input_query_class = class_embed(input_query_class) + + target_size = num_denoising_queries + num_queries + attn_mask = torch.full([target_size, target_size], 0, dtype=torch.float, device=device) + # match query cannot see the reconstruction + attn_mask[num_denoising_queries:, :num_denoising_queries] = -torch.inf + + # reconstructions cannot see each other + for i in range(num_groups_denoising_queries): + idx_block_start = max_gt_num * 2 * i + idx_block_end = max_gt_num * 2 * (i + 1) + attn_mask[idx_block_start:idx_block_end, :idx_block_start] = -torch.inf + attn_mask[idx_block_start:idx_block_end, idx_block_end:num_denoising_queries] = -torch.inf + + denoising_meta_values = { + "dn_positive_idx": denoise_positive_idx, + "dn_num_group": num_groups_denoising_queries, + "dn_num_split": [num_denoising_queries, num_queries], + } + + return input_query_class, input_query_bbox, attn_mask, denoising_meta_values + + +@auto_docstring( + custom_intro=""" + RT-DETR Model (consisting of a backbone and encoder-decoder) outputting raw hidden states without any head on top. + """ +) +class RTDetrModel(RTDetrPreTrainedModel): + def __init__(self, config: RTDetrConfig): + super().__init__(config) + + # Create backbone + self.backbone = RTDetrConvEncoder(config) + intermediate_channel_sizes = self.backbone.intermediate_channel_sizes + + # Create encoder input projection layers + # https://github.com/lyuwenyu/RT-DETR/blob/94f5e16708329d2f2716426868ec89aa774af016/rtdetr_pytorch/src/zoo/rtdetr/hybrid_encoder.py#L212 + num_backbone_outs = len(intermediate_channel_sizes) + encoder_input_proj_list = [] + for i in range(num_backbone_outs): + in_channels = intermediate_channel_sizes[i] + encoder_input_proj_list.append( + nn.Sequential( + nn.Conv2d(in_channels, config.encoder_hidden_dim, kernel_size=1, bias=False), + nn.BatchNorm2d(config.encoder_hidden_dim), + ) + ) + self.encoder_input_proj = nn.ModuleList(encoder_input_proj_list) + + # Create encoder + self.encoder = RTDetrHybridEncoder(config) + + # denoising part + if config.num_denoising > 0: + self.denoising_class_embed = nn.Embedding( + config.num_labels + 1, config.d_model, padding_idx=config.num_labels + ) + + # decoder embedding + if config.learn_initial_query: + self.weight_embedding = nn.Embedding(config.num_queries, config.d_model) + + # encoder head + self.enc_output = nn.Sequential( + nn.Linear(config.d_model, config.d_model), + nn.LayerNorm(config.d_model, eps=config.layer_norm_eps), + ) + self.enc_score_head = nn.Linear(config.d_model, config.num_labels) + self.enc_bbox_head = RTDetrMLPPredictionHead(config.d_model, config.d_model, 4, num_layers=3) + + # init encoder output anchors and valid_mask + if config.anchor_image_size: + self.anchors, self.valid_mask = self.generate_anchors(dtype=self.dtype) + + # Create decoder input projection layers + # https://github.com/lyuwenyu/RT-DETR/blob/94f5e16708329d2f2716426868ec89aa774af016/rtdetr_pytorch/src/zoo/rtdetr/rtdetr_decoder.py#L412 + num_backbone_outs = len(config.decoder_in_channels) + decoder_input_proj_list = [] + for i in range(num_backbone_outs): + in_channels = config.decoder_in_channels[i] + decoder_input_proj_list.append( + nn.Sequential( + nn.Conv2d(in_channels, config.d_model, kernel_size=1, bias=False), + nn.BatchNorm2d(config.d_model, config.batch_norm_eps), + ) + ) + for _ in range(config.num_feature_levels - num_backbone_outs): + decoder_input_proj_list.append( + nn.Sequential( + nn.Conv2d(in_channels, config.d_model, kernel_size=3, stride=2, padding=1, bias=False), + nn.BatchNorm2d(config.d_model, config.batch_norm_eps), + ) + ) + in_channels = config.d_model + self.decoder_input_proj = nn.ModuleList(decoder_input_proj_list) + + # decoder + self.decoder = RTDetrDecoder(config) + + self.post_init() + + def freeze_backbone(self): + for param in self.backbone.parameters(): + param.requires_grad_(False) + + def unfreeze_backbone(self): + for param in self.backbone.parameters(): + param.requires_grad_(True) + + @compile_compatible_method_lru_cache(maxsize=32) + def generate_anchors(self, spatial_shapes=None, grid_size=0.05, device="cpu", dtype=torch.float32): + if spatial_shapes is None: + spatial_shapes = [ + [int(self.config.anchor_image_size[0] / s), int(self.config.anchor_image_size[1] / s)] + for s in self.config.feat_strides + ] + anchors = [] + for level, (height, width) in enumerate(spatial_shapes): + grid_y, grid_x = torch.meshgrid( + torch.arange(end=height, device=device).to(dtype), + torch.arange(end=width, device=device).to(dtype), + indexing="ij", + ) + grid_xy = torch.stack([grid_x, grid_y], -1) + grid_xy = grid_xy.unsqueeze(0) + 0.5 + grid_xy[..., 0] /= width + grid_xy[..., 1] /= height + wh = torch.ones_like(grid_xy) * grid_size * (2.0**level) + anchors.append(torch.concat([grid_xy, wh], -1).reshape(-1, height * width, 4)) + # define the valid range for anchor coordinates + eps = 1e-2 + anchors = torch.concat(anchors, 1) + valid_mask = ((anchors > eps) * (anchors < 1 - eps)).all(-1, keepdim=True) + anchors = torch.log(anchors / (1 - anchors)) + anchors = torch.where(valid_mask, anchors, torch.tensor(torch.finfo(dtype).max, dtype=dtype, device=device)) + + return anchors, valid_mask + + @auto_docstring + @can_return_tuple + def forward( + self, + pixel_values: torch.FloatTensor, + pixel_mask: torch.LongTensor | None = None, + encoder_outputs: torch.FloatTensor | None = None, + inputs_embeds: torch.FloatTensor | None = None, + labels: list[dict] | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.FloatTensor] | RTDetrModelOutput: + r""" + inputs_embeds (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*): + Optionally, instead of passing the flattened feature map (output of the backbone + projection layer), you + can choose to directly pass a flattened representation of an image. + labels (`list[Dict]` of len `(batch_size,)`, *optional*): + Labels for computing the bipartite matching loss. List of dicts, each dictionary containing at least the + following 2 keys: 'class_labels' and 'boxes' (the class labels and bounding boxes of an image in the batch + respectively). The class labels themselves should be a `torch.LongTensor` of len `(number of bounding boxes + in the image,)` and the boxes a `torch.FloatTensor` of shape `(number of bounding boxes in the image, 4)`. + + Examples: + + ```python + >>> from transformers import AutoImageProcessor, RTDetrModel + >>> from PIL import Image + >>> import requests + + >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg" + >>> image = Image.open(requests.get(url, stream=True).raw) + + >>> image_processor = AutoImageProcessor.from_pretrained("PekingU/rtdetr_r50vd") + >>> model = RTDetrModel.from_pretrained("PekingU/rtdetr_r50vd") + + >>> inputs = image_processor(images=image, return_tensors="pt") + + >>> outputs = model(**inputs) + + >>> last_hidden_states = outputs.last_hidden_state + >>> list(last_hidden_states.shape) + [1, 300, 256] + ```""" + if pixel_values is None and inputs_embeds is None: + raise ValueError("You have to specify either pixel_values or inputs_embeds") + + if inputs_embeds is None: + batch_size, num_channels, height, width = pixel_values.shape + device = pixel_values.device + if pixel_mask is None: + pixel_mask = torch.ones(((batch_size, height, width)), device=device) + features = self.backbone(pixel_values, pixel_mask) + proj_feats = [self.encoder_input_proj[level](source) for level, (source, mask) in enumerate(features)] + else: + batch_size = inputs_embeds.shape[0] + device = inputs_embeds.device + proj_feats = inputs_embeds + + if encoder_outputs is None: + encoder_outputs = self.encoder( + proj_feats, + **kwargs, + ) + # If the user passed a tuple for encoder_outputs, we wrap it in a BaseModelOutput + elif not isinstance(encoder_outputs, BaseModelOutput): + encoder_outputs = BaseModelOutput( + last_hidden_state=encoder_outputs[0], + hidden_states=encoder_outputs[1] if len(encoder_outputs) > 1 else None, + attentions=encoder_outputs[2] if len(encoder_outputs) > 2 else None, + ) + + # Equivalent to def _get_encoder_input + # https://github.com/lyuwenyu/RT-DETR/blob/94f5e16708329d2f2716426868ec89aa774af016/rtdetr_pytorch/src/zoo/rtdetr/rtdetr_decoder.py#L412 + sources = [] + for level, source in enumerate(encoder_outputs.last_hidden_state): + sources.append(self.decoder_input_proj[level](source)) + + # Lowest resolution feature maps are obtained via 3x3 stride 2 convolutions on the final stage + if self.config.num_feature_levels > len(sources): + _len_sources = len(sources) + sources.append(self.decoder_input_proj[_len_sources](encoder_outputs.last_hidden_state)[-1]) + for i in range(_len_sources + 1, self.config.num_feature_levels): + sources.append(self.decoder_input_proj[i](encoder_outputs.last_hidden_state[-1])) + + # Prepare encoder inputs (by flattening) + source_flatten = [] + spatial_shapes_list = [] + spatial_shapes = torch.empty((len(sources), 2), device=device, dtype=torch.long) + for level, source in enumerate(sources): + height, width = source.shape[-2:] + spatial_shapes[level, 0] = height + spatial_shapes[level, 1] = width + spatial_shapes_list.append((height, width)) + source = source.flatten(2).transpose(1, 2) + source_flatten.append(source) + source_flatten = torch.cat(source_flatten, 1) + level_start_index = torch.cat((spatial_shapes.new_zeros((1,)), spatial_shapes.prod(1).cumsum(0)[:-1])) + + # prepare denoising training + if self.training and self.config.num_denoising > 0 and labels is not None: + ( + denoising_class, + denoising_bbox_unact, + attention_mask, + denoising_meta_values, + ) = get_contrastive_denoising_training_group( + targets=labels, + num_classes=self.config.num_labels, + num_queries=self.config.num_queries, + class_embed=self.denoising_class_embed, + num_denoising_queries=self.config.num_denoising, + label_noise_ratio=self.config.label_noise_ratio, + box_noise_scale=self.config.box_noise_scale, + ) + else: + denoising_class, denoising_bbox_unact, attention_mask, denoising_meta_values = None, None, None, None + + batch_size = len(source_flatten) + device = source_flatten.device + dtype = source_flatten.dtype + + # prepare input for decoder + if self.training or self.config.anchor_image_size is None: + # Pass spatial_shapes as tuple to make it hashable and make sure + # lru_cache is working for generate_anchors() + spatial_shapes_tuple = tuple(spatial_shapes_list) + anchors, valid_mask = self.generate_anchors(spatial_shapes_tuple, device=device, dtype=dtype) + else: + anchors, valid_mask = self.anchors, self.valid_mask + anchors, valid_mask = anchors.to(device, dtype), valid_mask.to(device, dtype) + + # use the valid_mask to selectively retain values in the feature map where the mask is `True` + memory = valid_mask.to(source_flatten.dtype) * source_flatten + + output_memory = self.enc_output(memory) + + enc_outputs_class = self.enc_score_head(output_memory) + enc_outputs_coord_logits = self.enc_bbox_head(output_memory) + anchors + + _, topk_ind = torch.topk(enc_outputs_class.max(-1).values, self.config.num_queries, dim=1) + + reference_points_unact = enc_outputs_coord_logits.gather( + dim=1, index=topk_ind.unsqueeze(-1).repeat(1, 1, enc_outputs_coord_logits.shape[-1]) + ) + + enc_topk_bboxes = F.sigmoid(reference_points_unact) + if denoising_bbox_unact is not None: + reference_points_unact = torch.concat([denoising_bbox_unact, reference_points_unact], 1) + + enc_topk_logits = enc_outputs_class.gather( + dim=1, index=topk_ind.unsqueeze(-1).repeat(1, 1, enc_outputs_class.shape[-1]) + ) + + # extract region features + if self.config.learn_initial_query: + target = self.weight_embedding.tile([batch_size, 1, 1]) + else: + target = output_memory.gather(dim=1, index=topk_ind.unsqueeze(-1).repeat(1, 1, output_memory.shape[-1])) + target = target.detach() + + if denoising_class is not None: + target = torch.concat([denoising_class, target], 1) + + init_reference_points = reference_points_unact.detach() + + # decoder + decoder_outputs = self.decoder( + inputs_embeds=target, + encoder_hidden_states=source_flatten, + encoder_attention_mask=attention_mask, + reference_points=init_reference_points, + spatial_shapes=spatial_shapes, + spatial_shapes_list=spatial_shapes_list, + level_start_index=level_start_index, + **kwargs, + ) + + return RTDetrModelOutput( + last_hidden_state=decoder_outputs.last_hidden_state, + intermediate_hidden_states=decoder_outputs.intermediate_hidden_states, + intermediate_logits=decoder_outputs.intermediate_logits, + intermediate_reference_points=decoder_outputs.intermediate_reference_points, + intermediate_predicted_corners=decoder_outputs.intermediate_predicted_corners, + initial_reference_points=decoder_outputs.initial_reference_points, + decoder_hidden_states=decoder_outputs.hidden_states, + decoder_attentions=decoder_outputs.attentions, + cross_attentions=decoder_outputs.cross_attentions, + encoder_last_hidden_state=encoder_outputs.last_hidden_state, + encoder_hidden_states=encoder_outputs.hidden_states, + encoder_attentions=encoder_outputs.attentions, + init_reference_points=init_reference_points, + enc_topk_logits=enc_topk_logits, + enc_topk_bboxes=enc_topk_bboxes, + enc_outputs_class=enc_outputs_class, + enc_outputs_coord_logits=enc_outputs_coord_logits, + denoising_meta_values=denoising_meta_values, + ) + + +@auto_docstring( + custom_intro=""" + RT-DETR Model (consisting of a backbone and encoder-decoder) outputting bounding boxes and logits to be further + decoded into scores and classes. + """ +) +class RTDetrForObjectDetection(RTDetrPreTrainedModel): + # When using clones, all layers > 0 will be clones, but layer 0 *is* required + # We can't initialize the model on meta device as some weights are modified during the initialization + _no_split_modules = None + + def __init__(self, config: RTDetrConfig): + super().__init__(config) + self.model = RTDetrModel(config) + num_pred = config.decoder_layers + self.model.decoder.class_embed = nn.ModuleList( + [torch.nn.Linear(config.d_model, config.num_labels) for _ in range(num_pred)] + ) + self.model.decoder.bbox_embed = nn.ModuleList( + [RTDetrMLPPredictionHead(config.d_model, config.d_model, 4, num_layers=3) for _ in range(num_pred)] + ) + # if two-stage, the last class_embed and bbox_embed is for region proposal generation + self.post_init() + + def _set_aux_loss(self, outputs_class, outputs_coord): + return [{"logits": a, "pred_boxes": b} for a, b in zip(outputs_class, outputs_coord)] + + @auto_docstring + @can_return_tuple + def forward( + self, + pixel_values: torch.FloatTensor, + pixel_mask: torch.LongTensor | None = None, + encoder_outputs: torch.FloatTensor | None = None, + inputs_embeds: torch.FloatTensor | None = None, + labels: list[dict] | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.FloatTensor] | RTDetrObjectDetectionOutput: + r""" + inputs_embeds (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*): + Optionally, instead of passing the flattened feature map (output of the backbone + projection layer), you + can choose to directly pass a flattened representation of an image. + labels (`list[Dict]` of len `(batch_size,)`, *optional*): + Labels for computing the bipartite matching loss. List of dicts, each dictionary containing at least the + following 2 keys: 'class_labels' and 'boxes' (the class labels and bounding boxes of an image in the batch + respectively). The class labels themselves should be a `torch.LongTensor` of len `(number of bounding boxes + in the image,)` and the boxes a `torch.FloatTensor` of shape `(number of bounding boxes in the image, 4)`. + + Examples: + + ```python + >>> from transformers import RTDetrImageProcessor, RTDetrForObjectDetection + >>> from PIL import Image + >>> import requests + >>> import torch + + >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg" + >>> image = Image.open(requests.get(url, stream=True).raw) + + >>> image_processor = RTDetrImageProcessor.from_pretrained("PekingU/rtdetr_r50vd") + >>> model = RTDetrForObjectDetection.from_pretrained("PekingU/rtdetr_r50vd") + + >>> # prepare image for the model + >>> inputs = image_processor(images=image, return_tensors="pt") + + >>> # forward pass + >>> outputs = model(**inputs) + + >>> logits = outputs.logits + >>> list(logits.shape) + [1, 300, 80] + + >>> boxes = outputs.pred_boxes + >>> list(boxes.shape) + [1, 300, 4] + + >>> # convert outputs (bounding boxes and class logits) to Pascal VOC format (xmin, ymin, xmax, ymax) + >>> target_sizes = torch.tensor([image.size[::-1]]) + >>> results = image_processor.post_process_object_detection(outputs, threshold=0.9, target_sizes=target_sizes)[ + ... 0 + ... ] + + >>> for score, label, box in zip(results["scores"], results["labels"], results["boxes"]): + ... box = [round(i, 2) for i in box.tolist()] + ... print( + ... f"Detected {model.config.id2label[label.item()]} with confidence " + ... f"{round(score.item(), 3)} at location {box}" + ... ) + Detected sofa with confidence 0.97 at location [0.14, 0.38, 640.13, 476.21] + Detected cat with confidence 0.96 at location [343.38, 24.28, 640.14, 371.5] + Detected cat with confidence 0.958 at location [13.23, 54.18, 318.98, 472.22] + Detected remote with confidence 0.951 at location [40.11, 73.44, 175.96, 118.48] + Detected remote with confidence 0.924 at location [333.73, 76.58, 369.97, 186.99] + ```""" + outputs = self.model( + pixel_values, + pixel_mask=pixel_mask, + encoder_outputs=encoder_outputs, + inputs_embeds=inputs_embeds, + labels=labels, + **kwargs, + ) + + denoising_meta_values = outputs.denoising_meta_values if self.training else None + + outputs_class = outputs.intermediate_logits + outputs_coord = outputs.intermediate_reference_points + predicted_corners = outputs.intermediate_predicted_corners + initial_reference_points = outputs.initial_reference_points + + logits = outputs_class[:, -1] + pred_boxes = outputs_coord[:, -1] + + loss, loss_dict, auxiliary_outputs, enc_topk_logits, enc_topk_bboxes = None, None, None, None, None + if labels is not None: + enc_topk_logits = outputs.enc_topk_logits + enc_topk_bboxes = outputs.enc_topk_bboxes + loss, loss_dict, auxiliary_outputs = self.loss_function( + logits, + labels, + self.device, + pred_boxes, + self.config, + outputs_class, + outputs_coord, + enc_topk_logits=enc_topk_logits, + enc_topk_bboxes=enc_topk_bboxes, + denoising_meta_values=denoising_meta_values, + predicted_corners=predicted_corners, + initial_reference_points=initial_reference_points, + **kwargs, + ) + + return RTDetrObjectDetectionOutput( + loss=loss, + loss_dict=loss_dict, + logits=logits, + pred_boxes=pred_boxes, + auxiliary_outputs=auxiliary_outputs, + last_hidden_state=outputs.last_hidden_state, + intermediate_hidden_states=outputs.intermediate_hidden_states, + intermediate_logits=outputs.intermediate_logits, + intermediate_reference_points=outputs.intermediate_reference_points, + intermediate_predicted_corners=outputs.intermediate_predicted_corners, + initial_reference_points=outputs.initial_reference_points, + decoder_hidden_states=outputs.decoder_hidden_states, + decoder_attentions=outputs.decoder_attentions, + cross_attentions=outputs.cross_attentions, + encoder_last_hidden_state=outputs.encoder_last_hidden_state, + encoder_hidden_states=outputs.encoder_hidden_states, + encoder_attentions=outputs.encoder_attentions, + init_reference_points=outputs.init_reference_points, + enc_topk_logits=outputs.enc_topk_logits, + enc_topk_bboxes=outputs.enc_topk_bboxes, + enc_outputs_class=outputs.enc_outputs_class, + enc_outputs_coord_logits=outputs.enc_outputs_coord_logits, + denoising_meta_values=outputs.denoising_meta_values, + ) + + +__all__ = ["RTDetrForObjectDetection", "RTDetrModel", "RTDetrPreTrainedModel"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/rt_detr/modeling_rt_detr_resnet.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/rt_detr/modeling_rt_detr_resnet.py new file mode 100644 index 0000000000000000000000000000000000000000..a79afaf88b1e96ccebb639745d1a15dd5b4eee02 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/rt_detr/modeling_rt_detr_resnet.py @@ -0,0 +1,409 @@ +# Copyright 2024 Microsoft Research, Inc. and The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +""" +PyTorch RTDetr specific ResNet model. The main difference between hugginface ResNet model is that this RTDetrResNet model forces to use shortcut at the first layer in the resnet-18/34 models. +See https://github.com/lyuwenyu/RT-DETR/blob/5b628eaa0a2fc25bdafec7e6148d5296b144af85/rtdetr_pytorch/src/nn/backbone/presnet.py#L126 for details. +""" + +import math + +import torch +from torch import Tensor, nn + +from ... import initialization as init +from ...activations import ACT2FN +from ...backbone_utils import BackboneMixin +from ...modeling_outputs import BackboneOutput, BaseModelOutputWithNoAttention +from ...modeling_utils import PreTrainedModel +from ...utils import auto_docstring, logging +from .configuration_rt_detr_resnet import RTDetrResNetConfig + + +logger = logging.get_logger(__name__) + + +# Copied from transformers.models.resnet.modeling_resnet.ResNetConvLayer -> RTDetrResNetConvLayer +class RTDetrResNetConvLayer(nn.Module): + def __init__( + self, in_channels: int, out_channels: int, kernel_size: int = 3, stride: int = 1, activation: str = "relu" + ): + super().__init__() + self.convolution = nn.Conv2d( + in_channels, out_channels, kernel_size=kernel_size, stride=stride, padding=kernel_size // 2, bias=False + ) + self.normalization = nn.BatchNorm2d(out_channels) + self.activation = ACT2FN[activation] if activation is not None else nn.Identity() + + def forward(self, input: Tensor) -> Tensor: + hidden_state = self.convolution(input) + hidden_state = self.normalization(hidden_state) + hidden_state = self.activation(hidden_state) + return hidden_state + + +class RTDetrResNetEmbeddings(nn.Module): + """ + ResNet Embeddings (stem) composed of a deep aggressive convolution. + """ + + def __init__(self, config: RTDetrResNetConfig): + super().__init__() + self.embedder = nn.Sequential( + *[ + RTDetrResNetConvLayer( + config.num_channels, + config.embedding_size // 2, + kernel_size=3, + stride=2, + activation=config.hidden_act, + ), + RTDetrResNetConvLayer( + config.embedding_size // 2, + config.embedding_size // 2, + kernel_size=3, + stride=1, + activation=config.hidden_act, + ), + RTDetrResNetConvLayer( + config.embedding_size // 2, + config.embedding_size, + kernel_size=3, + stride=1, + activation=config.hidden_act, + ), + ] + ) + self.pooler = nn.MaxPool2d(kernel_size=3, stride=2, padding=1) + self.num_channels = config.num_channels + + def forward(self, pixel_values: Tensor) -> Tensor: + num_channels = pixel_values.shape[1] + if num_channels != self.num_channels: + raise ValueError( + "Make sure that the channel dimension of the pixel values match with the one set in the configuration." + ) + embedding = self.embedder(pixel_values) + embedding = self.pooler(embedding) + return embedding + + +# Copied from transformers.models.resnet.modeling_resnet.ResNetShortCut -> RTDetrResNetChortCut +class RTDetrResNetShortCut(nn.Module): + """ + ResNet shortcut, used to project the residual features to the correct size. If needed, it is also used to + downsample the input using `stride=2`. + """ + + def __init__(self, in_channels: int, out_channels: int, stride: int = 2): + super().__init__() + self.convolution = nn.Conv2d(in_channels, out_channels, kernel_size=1, stride=stride, bias=False) + self.normalization = nn.BatchNorm2d(out_channels) + + def forward(self, input: Tensor) -> Tensor: + hidden_state = self.convolution(input) + hidden_state = self.normalization(hidden_state) + return hidden_state + + +class RTDetrResNetBasicLayer(nn.Module): + """ + A classic ResNet's residual layer composed by two `3x3` convolutions. + See https://github.com/lyuwenyu/RT-DETR/blob/5b628eaa0a2fc25bdafec7e6148d5296b144af85/rtdetr_pytorch/src/nn/backbone/presnet.py#L34. + """ + + def __init__( + self, + config: RTDetrResNetConfig, + in_channels: int, + out_channels: int, + stride: int = 1, + should_apply_shortcut: bool = False, + ): + super().__init__() + if in_channels != out_channels: + self.shortcut = ( + nn.Sequential( + *[nn.AvgPool2d(2, 2, 0, ceil_mode=True), RTDetrResNetShortCut(in_channels, out_channels, stride=1)] + ) + if should_apply_shortcut + else nn.Identity() + ) + else: + self.shortcut = ( + RTDetrResNetShortCut(in_channels, out_channels, stride=stride) + if should_apply_shortcut + else nn.Identity() + ) + self.layer = nn.Sequential( + RTDetrResNetConvLayer(in_channels, out_channels, stride=stride), + RTDetrResNetConvLayer(out_channels, out_channels, activation=None), + ) + self.activation = ACT2FN[config.hidden_act] + + def forward(self, hidden_state): + residual = hidden_state + hidden_state = self.layer(hidden_state) + residual = self.shortcut(residual) + hidden_state += residual + hidden_state = self.activation(hidden_state) + return hidden_state + + +class RTDetrResNetBottleNeckLayer(nn.Module): + """ + A classic RTDetrResNet's bottleneck layer composed by three `3x3` convolutions. + + The first `1x1` convolution reduces the input by a factor of `reduction` in order to make the second `3x3` + convolution faster. The last `1x1` convolution remaps the reduced features to `out_channels`. If + `downsample_in_bottleneck` is true, downsample will be in the first layer instead of the second layer. + """ + + def __init__( + self, + config: RTDetrResNetConfig, + in_channels: int, + out_channels: int, + stride: int = 1, + ): + super().__init__() + reduction = 4 + should_apply_shortcut = in_channels != out_channels or stride != 1 + reduces_channels = out_channels // reduction + if stride == 2: + self.shortcut = nn.Sequential( + *[ + nn.AvgPool2d(2, 2, 0, ceil_mode=True), + RTDetrResNetShortCut(in_channels, out_channels, stride=1) + if should_apply_shortcut + else nn.Identity(), + ] + ) + else: + self.shortcut = ( + RTDetrResNetShortCut(in_channels, out_channels, stride=stride) + if should_apply_shortcut + else nn.Identity() + ) + self.layer = nn.Sequential( + RTDetrResNetConvLayer( + in_channels, reduces_channels, kernel_size=1, stride=stride if config.downsample_in_bottleneck else 1 + ), + RTDetrResNetConvLayer( + reduces_channels, reduces_channels, stride=stride if not config.downsample_in_bottleneck else 1 + ), + RTDetrResNetConvLayer(reduces_channels, out_channels, kernel_size=1, activation=None), + ) + self.activation = ACT2FN[config.hidden_act] + + def forward(self, hidden_state): + residual = hidden_state + hidden_state = self.layer(hidden_state) + residual = self.shortcut(residual) + hidden_state += residual + hidden_state = self.activation(hidden_state) + return hidden_state + + +class RTDetrResNetStage(nn.Module): + """ + A RTDetrResNet stage composed by stacked layers. + """ + + def __init__( + self, + config: RTDetrResNetConfig, + in_channels: int, + out_channels: int, + stride: int = 2, + depth: int = 2, + ): + super().__init__() + + layer = RTDetrResNetBottleNeckLayer if config.layer_type == "bottleneck" else RTDetrResNetBasicLayer + + if config.layer_type == "bottleneck": + first_layer = layer( + config, + in_channels, + out_channels, + stride=stride, + ) + else: + first_layer = layer(config, in_channels, out_channels, stride=stride, should_apply_shortcut=True) + self.layers = nn.Sequential( + first_layer, *[layer(config, out_channels, out_channels) for _ in range(depth - 1)] + ) + + def forward(self, input: Tensor) -> Tensor: + hidden_state = input + for layer in self.layers: + hidden_state = layer(hidden_state) + return hidden_state + + +# Copied from transformers.models.resnet.modeling_resnet.ResNetEncoder with ResNet->RTDetrResNet +class RTDetrResNetEncoder(nn.Module): + def __init__(self, config: RTDetrResNetConfig): + super().__init__() + self.stages = nn.ModuleList([]) + # based on `downsample_in_first_stage` the first layer of the first stage may or may not downsample the input + self.stages.append( + RTDetrResNetStage( + config, + config.embedding_size, + config.hidden_sizes[0], + stride=2 if config.downsample_in_first_stage else 1, + depth=config.depths[0], + ) + ) + in_out_channels = zip(config.hidden_sizes, config.hidden_sizes[1:]) + for (in_channels, out_channels), depth in zip(in_out_channels, config.depths[1:]): + self.stages.append(RTDetrResNetStage(config, in_channels, out_channels, depth=depth)) + + def forward( + self, hidden_state: Tensor, output_hidden_states: bool = False, return_dict: bool = True + ) -> BaseModelOutputWithNoAttention: + hidden_states = () if output_hidden_states else None + + for stage_module in self.stages: + if output_hidden_states: + hidden_states = hidden_states + (hidden_state,) + + hidden_state = stage_module(hidden_state) + + if output_hidden_states: + hidden_states = hidden_states + (hidden_state,) + + if not return_dict: + return tuple(v for v in [hidden_state, hidden_states] if v is not None) + + return BaseModelOutputWithNoAttention( + last_hidden_state=hidden_state, + hidden_states=hidden_states, + ) + + +@auto_docstring +# Copied from transformers.models.resnet.modeling_resnet.ResNetPreTrainedModel with ResNet->RTDetrResNet +class RTDetrResNetPreTrainedModel(PreTrainedModel): + config: RTDetrResNetConfig + base_model_prefix = "resnet" + main_input_name = "pixel_values" + input_modalities = ("image",) + _no_split_modules = ["RTDetrResNetConvLayer", "RTDetrResNetShortCut"] + + @torch.no_grad() + def _init_weights(self, module): + if isinstance(module, nn.Conv2d): + init.kaiming_normal_(module.weight, mode="fan_out", nonlinearity="relu") + # copied from the `reset_parameters` method of `class Linear(Module)` in `torch`. + elif isinstance(module, nn.Linear): + init.kaiming_uniform_(module.weight, a=math.sqrt(5)) + if module.bias is not None: + fan_in, _ = torch.nn.init._calculate_fan_in_and_fan_out(module.weight) + bound = 1 / math.sqrt(fan_in) if fan_in > 0 else 0 + init.uniform_(module.bias, -bound, bound) + # We need to check it like that as some Detr models replace the BatchNorm2d by their own + elif "BatchNorm" in module.__class__.__name__: + init.ones_(module.weight) + init.zeros_(module.bias) + init.zeros_(module.running_mean) + init.ones_(module.running_var) + if getattr(module, "num_batches_tracked", None) is not None: + init.zeros_(module.num_batches_tracked) + + +@auto_docstring( + custom_intro=""" + ResNet backbone, to be used with frameworks like RTDETR. + """ +) +class RTDetrResNetBackbone(BackboneMixin, RTDetrResNetPreTrainedModel): + has_attentions = False + + def __init__(self, config): + super().__init__(config) + + self.num_features = [config.embedding_size] + config.hidden_sizes + self.embedder = RTDetrResNetEmbeddings(config) + self.encoder = RTDetrResNetEncoder(config) + + # initialize weights and apply final processing + self.post_init() + + @auto_docstring + def forward( + self, + pixel_values: Tensor, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + **kwargs, + ) -> BackboneOutput: + r""" + Examples: + + ```python + >>> from transformers import RTDetrResNetConfig, RTDetrResNetBackbone + >>> import torch + from ...utils.deprecation import deprecate_kwarg + from ...utils.deprecation import deprecate_kwarg + from ...utils.deprecation import deprecate_kwarg + from ...utils.deprecation import deprecate_kwarg + from ...utils.deprecation import deprecate_kwarg + + >>> config = RTDetrResNetConfig() + >>> model = RTDetrResNetBackbone(config) + + >>> pixel_values = torch.randn(1, 3, 224, 224) + + >>> with torch.no_grad(): + ... outputs = model(pixel_values) + + >>> feature_maps = outputs.feature_maps + >>> list(feature_maps[-1].shape) + [1, 2048, 7, 7] + ```""" + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + + embedding_output = self.embedder(pixel_values) + + outputs = self.encoder(embedding_output, output_hidden_states=True, return_dict=True) + + hidden_states = outputs.hidden_states + + feature_maps = () + for idx, stage in enumerate(self.stage_names): + if stage in self.out_features: + feature_maps += (hidden_states[idx],) + + if not return_dict: + output = (feature_maps,) + if output_hidden_states: + output += (outputs.hidden_states,) + return output + + return BackboneOutput( + feature_maps=feature_maps, + hidden_states=outputs.hidden_states if output_hidden_states else None, + attentions=None, + ) + + +__all__ = [ + "RTDetrResNetBackbone", + "RTDetrResNetPreTrainedModel", +] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/rt_detr/modular_rt_detr.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/rt_detr/modular_rt_detr.py new file mode 100644 index 0000000000000000000000000000000000000000..f9289f9e66196d913b876076c245aeb4e13b8e0e --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/rt_detr/modular_rt_detr.py @@ -0,0 +1,1832 @@ +# Copyright 2024 Baidu Inc and The HuggingFace Inc. team. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +import math +import pathlib +from dataclasses import dataclass +from typing import Optional + +import torch +import torch.nn.functional as F +import torchvision.transforms.v2.functional as tvF +from torch import nn + +from ... import initialization as init +from ...activations import ACT2CLS, ACT2FN +from ...backbone_utils import load_backbone +from ...image_processing_utils import BatchFeature +from ...image_processing_utils_fast import BaseImageProcessorFast, SizeDict, get_max_height_width +from ...image_transforms import center_to_corners_format, corners_to_center_format +from ...image_utils import ( + IMAGENET_DEFAULT_MEAN, + IMAGENET_DEFAULT_STD, + AnnotationFormat, + AnnotationType, + ChannelDimension, + PILImageResampling, + get_image_size, + validate_annotations, +) +from ...modeling_outputs import BaseModelOutput +from ...modeling_utils import PreTrainedModel +from ...processing_utils import Unpack +from ...pytorch_utils import compile_compatible_method_lru_cache +from ...utils import ( + ModelOutput, + TensorType, + TransformersKwargs, + auto_docstring, + logging, + requires_backends, + torch_int, +) +from ...utils.generic import can_return_tuple, merge_with_config_defaults +from ...utils.output_capturing import capture_outputs +from ..conditional_detr.modeling_conditional_detr import inverse_sigmoid +from ..deformable_detr.modeling_deformable_detr import DeformableDetrMultiscaleDeformableAttention +from ..detr.image_processing_detr_fast import DetrImageProcessorFast +from ..detr.modeling_detr import DetrFrozenBatchNorm2d, DetrMLPPredictionHead, DetrSelfAttention, replace_batch_norm +from .configuration_rt_detr import RTDetrConfig +from .image_processing_rt_detr import RTDetrImageProcessorKwargs + + +logger = logging.get_logger(__name__) + +SUPPORTED_ANNOTATION_FORMATS = (AnnotationFormat.COCO_DETECTION,) + + +def prepare_coco_detection_annotation( + image, + target, + return_segmentation_masks: bool = False, + input_data_format: ChannelDimension | str | None = None, +): + """ + Convert the target in COCO format into the format expected by RT-DETR. + """ + image_height, image_width = image.size()[-2:] + + image_id = target["image_id"] + image_id = torch.as_tensor([image_id], dtype=torch.int64, device=image.device) + + # Get all COCO annotations for the given image. + annotations = target["annotations"] + classes = [] + area = [] + boxes = [] + keypoints = [] + for obj in annotations: + if "iscrowd" not in obj or obj["iscrowd"] == 0: + classes.append(obj["category_id"]) + area.append(obj["area"]) + boxes.append(obj["bbox"]) + if "keypoints" in obj: + keypoints.append(obj["keypoints"]) + + classes = torch.as_tensor(classes, dtype=torch.int64, device=image.device) + area = torch.as_tensor(area, dtype=torch.float32, device=image.device) + iscrowd = torch.zeros_like(classes, dtype=torch.int64, device=image.device) + # guard against no boxes via resizing + boxes = torch.as_tensor(boxes, dtype=torch.float32, device=image.device).reshape(-1, 4) + boxes[:, 2:] += boxes[:, :2] + boxes[:, 0::2] = boxes[:, 0::2].clip(min=0, max=image_width) + boxes[:, 1::2] = boxes[:, 1::2].clip(min=0, max=image_height) + + keep = (boxes[:, 3] > boxes[:, 1]) & (boxes[:, 2] > boxes[:, 0]) + + new_target = { + "image_id": image_id, + "class_labels": classes[keep], + "boxes": boxes[keep], + "area": area[keep], + "iscrowd": iscrowd[keep], + "orig_size": torch.as_tensor([int(image_height), int(image_width)], dtype=torch.int64, device=image.device), + } + + if keypoints: + keypoints = torch.as_tensor(keypoints, dtype=torch.float32, device=image.device) + # Apply the keep mask here to filter the relevant annotations + keypoints = keypoints[keep] + num_keypoints = keypoints.shape[0] + keypoints = keypoints.reshape((-1, 3)) if num_keypoints else keypoints + new_target["keypoints"] = keypoints + + return new_target + + +class RTDetrImageProcessorFast(DetrImageProcessorFast): + resample = PILImageResampling.BILINEAR + image_mean = IMAGENET_DEFAULT_MEAN + image_std = IMAGENET_DEFAULT_STD + format = AnnotationFormat.COCO_DETECTION + do_convert_annotations = True + do_resize = True + do_rescale = True + do_normalize = False + do_pad = False + size = {"height": 640, "width": 640} + default_to_square = False + model_input_names = ["pixel_values", "pixel_mask"] + valid_kwargs = RTDetrImageProcessorKwargs + + def __init__(self, **kwargs: Unpack[RTDetrImageProcessorKwargs]) -> None: + # Backwards compatibility + do_convert_annotations = kwargs.get("do_convert_annotations") + do_normalize = kwargs.get("do_normalize") + if do_convert_annotations is None and getattr(self, "do_convert_annotations", None) is None: + self.do_convert_annotations = do_normalize if do_normalize is not None else self.do_normalize + + BaseImageProcessorFast.__init__(self, **kwargs) + + def prepare_annotation( + self, + image: torch.Tensor, + target: dict, + format: AnnotationFormat | None = None, + return_segmentation_masks: bool | None = None, + masks_path: str | pathlib.Path | None = None, + input_data_format: str | ChannelDimension | None = None, + ) -> dict: + format = format if format is not None else self.format + + if format == AnnotationFormat.COCO_DETECTION: + return_segmentation_masks = False if return_segmentation_masks is None else return_segmentation_masks + target = prepare_coco_detection_annotation( + image, target, return_segmentation_masks, input_data_format=input_data_format + ) + else: + raise ValueError(f"Format {format} is not supported.") + return target + + def _preprocess( + self, + images: list["torch.Tensor"], + annotations: AnnotationType | list[AnnotationType] | None, + masks_path: str | pathlib.Path | None, + return_segmentation_masks: bool, + do_resize: bool, + size: SizeDict, + interpolation: Optional["tvF.InterpolationMode"], + do_rescale: bool, + rescale_factor: float, + do_normalize: bool, + do_convert_annotations: bool, + image_mean: float | list[float] | None, + image_std: float | list[float] | None, + do_pad: bool, + pad_size: SizeDict | None, + format: str | AnnotationFormat | None, + return_tensors: str | TensorType | None, + **kwargs, + ) -> BatchFeature: + """ + Preprocess an image or a batch of images so that it can be used by the model. + """ + + if annotations is not None and isinstance(annotations, dict): + annotations = [annotations] + + if annotations is not None and len(images) != len(annotations): + raise ValueError( + f"The number of images ({len(images)}) and annotations ({len(annotations)}) do not match." + ) + + format = AnnotationFormat(format) + if annotations is not None: + validate_annotations(format, SUPPORTED_ANNOTATION_FORMATS, annotations) + + data = {} + processed_images = [] + processed_annotations = [] + pixel_masks = [] # Initialize pixel_masks here + for image, annotation in zip(images, annotations if annotations is not None else [None] * len(images)): + # prepare (COCO annotations as a list of Dict -> DETR target as a single Dict per image) + if annotations is not None: + annotation = self.prepare_annotation( + image, + annotation, + format, + return_segmentation_masks=return_segmentation_masks, + masks_path=masks_path, + input_data_format=ChannelDimension.FIRST, + ) + + if do_resize: + resized_image = self.resize(image, size=size, interpolation=interpolation) + if annotations is not None: + annotation = self.resize_annotation( + annotation, + orig_size=image.size()[-2:], + target_size=resized_image.size()[-2:], + ) + image = resized_image + # Fused rescale and normalize + image = self.rescale_and_normalize(image, do_rescale, rescale_factor, do_normalize, image_mean, image_std) + if do_convert_annotations and annotations is not None: + annotation = self.normalize_annotation(annotation, get_image_size(image, ChannelDimension.FIRST)) + + processed_images.append(image) + processed_annotations.append(annotation) + images = processed_images + annotations = processed_annotations if annotations is not None else None + + if do_pad: + # depends on all resized image shapes so we need another loop + if pad_size is not None: + padded_size = (pad_size.height, pad_size.width) + else: + padded_size = get_max_height_width(images) + + padded_images = [] + padded_annotations = [] + for image, annotation in zip(images, annotations if annotations is not None else [None] * len(images)): + # Pads images and returns their mask: {'pixel_values': ..., 'pixel_mask': ...} + if padded_size == image.size()[-2:]: + padded_images.append(image) + pixel_masks.append(torch.ones(padded_size, dtype=torch.int64, device=image.device)) + padded_annotations.append(annotation) + continue + image, pixel_mask, annotation = self.pad( + image, padded_size, annotation=annotation, update_bboxes=do_convert_annotations + ) + padded_images.append(image) + padded_annotations.append(annotation) + pixel_masks.append(pixel_mask) + images = padded_images + annotations = padded_annotations if annotations is not None else None + data.update({"pixel_mask": torch.stack(pixel_masks, dim=0)}) + + data.update({"pixel_values": torch.stack(images, dim=0)}) + encoded_inputs = BatchFeature(data, tensor_type=return_tensors) + if annotations is not None: + encoded_inputs["labels"] = [ + BatchFeature(annotation, tensor_type=return_tensors) for annotation in annotations + ] + return encoded_inputs + + def post_process_object_detection( + self, + outputs, + threshold: float = 0.5, + target_sizes: TensorType | list[tuple] = None, + use_focal_loss: bool = True, + ): + """ + Converts the raw output of [`DetrForObjectDetection`] into final bounding boxes in (top_left_x, top_left_y, + bottom_right_x, bottom_right_y) format. Only supports PyTorch. + + Args: + outputs ([`DetrObjectDetectionOutput`]): + Raw outputs of the model. + threshold (`float`, *optional*, defaults to 0.5): + Score threshold to keep object detection predictions. + target_sizes (`torch.Tensor` or `list[tuple[int, int]]`, *optional*): + Tensor of shape `(batch_size, 2)` or list of tuples (`tuple[int, int]`) containing the target size + `(height, width)` of each image in the batch. If unset, predictions will not be resized. + use_focal_loss (`bool` defaults to `True`): + Variable informing if the focal loss was used to predict the outputs. If `True`, a sigmoid is applied + to compute the scores of each detection, otherwise, a softmax function is used. + + Returns: + `list[Dict]`: A list of dictionaries, each dictionary containing the scores, labels and boxes for an image + in the batch as predicted by the model. + """ + requires_backends(self, ["torch"]) + out_logits, out_bbox = outputs.logits, outputs.pred_boxes + # convert from relative cxcywh to absolute xyxy + boxes = center_to_corners_format(out_bbox) + if target_sizes is not None: + if len(out_logits) != len(target_sizes): + raise ValueError( + "Make sure that you pass in as many target sizes as the batch dimension of the logits" + ) + if isinstance(target_sizes, list): + img_h, img_w = torch.as_tensor(target_sizes).unbind(1) + else: + img_h, img_w = target_sizes.unbind(1) + scale_fct = torch.stack([img_w, img_h, img_w, img_h], dim=1).to(boxes.device) + boxes = boxes * scale_fct[:, None, :] + + num_top_queries = out_logits.shape[1] + num_classes = out_logits.shape[2] + + if use_focal_loss: + scores = torch.nn.functional.sigmoid(out_logits) + scores, index = torch.topk(scores.flatten(1), num_top_queries, axis=-1) + labels = index % num_classes + index = index // num_classes + boxes = boxes.gather(dim=1, index=index.unsqueeze(-1).repeat(1, 1, boxes.shape[-1])) + else: + scores = torch.nn.functional.softmax(out_logits)[:, :, :-1] + scores, labels = scores.max(dim=-1) + if scores.shape[1] > num_top_queries: + scores, index = torch.topk(scores, num_top_queries, dim=-1) + labels = torch.gather(labels, dim=1, index=index) + boxes = torch.gather(boxes, dim=1, index=index.unsqueeze(-1).tile(1, 1, boxes.shape[-1])) + + results = [] + for score, label, box in zip(scores, labels, boxes): + results.append( + { + "scores": score[score > threshold], + "labels": label[score > threshold], + "boxes": box[score > threshold], + } + ) + + return results + + def post_process_instance_segmentation(self): + raise NotImplementedError("Segmentation post-processing is not implemented for RT-DETR yet.") + + def post_process_semantic_segmentation(self): + raise NotImplementedError("Semantic segmentation post-processing is not implemented for RT-DETR yet.") + + def post_process_panoptic_segmentation(self): + raise NotImplementedError("Panoptic segmentation post-processing is not implemented for RT-DETR yet.") + + +@dataclass +@auto_docstring( + custom_intro=""" + Base class for outputs of the RTDetrDecoder. This class adds two attributes to + BaseModelOutputWithCrossAttentions, namely: + - a stacked tensor of intermediate decoder hidden states (i.e. the output of each decoder layer) + - a stacked tensor of intermediate reference points. + """ +) +class RTDetrDecoderOutput(ModelOutput): + r""" + intermediate_hidden_states (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, hidden_size)`): + Stacked intermediate hidden states (output of each layer of the decoder). + intermediate_logits (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, sequence_length, config.num_labels)`): + Stacked intermediate logits (logits of each layer of the decoder). + intermediate_reference_points (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, sequence_length, hidden_size)`): + Stacked intermediate reference points (reference points of each layer of the decoder). + intermediate_predicted_corners (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, 4)`): + Stacked intermediate predicted corners (predicted corners of each layer of the decoder). + initial_reference_points (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, 4)`): + Stacked initial reference points (initial reference points of each layer of the decoder). + cross_attentions (`tuple(torch.FloatTensor)`, *optional*, returned when `output_attentions=True` and `config.add_cross_attention=True` is passed or when `config.output_attentions=True`): + Tuple of `torch.FloatTensor` (one for each layer) of shape `(batch_size, num_heads, sequence_length, + sequence_length)`. Attentions weights of the decoder's cross-attention layer, after the attention softmax, + used to compute the weighted average in the cross-attention heads. + """ + + last_hidden_state: torch.FloatTensor | None = None + intermediate_hidden_states: torch.FloatTensor | None = None + intermediate_logits: torch.FloatTensor | None = None + intermediate_reference_points: torch.FloatTensor | None = None + intermediate_predicted_corners: torch.FloatTensor | None = None + initial_reference_points: torch.FloatTensor | None = None + hidden_states: tuple[torch.FloatTensor] | None = None + attentions: tuple[torch.FloatTensor] | None = None + cross_attentions: tuple[torch.FloatTensor] | None = None + + +@dataclass +@auto_docstring( + custom_intro=""" + Base class for outputs of the RT-DETR encoder-decoder model. + """ +) +class RTDetrModelOutput(ModelOutput): + r""" + last_hidden_state (`torch.FloatTensor` of shape `(batch_size, num_queries, hidden_size)`): + Sequence of hidden-states at the output of the last layer of the decoder of the model. + intermediate_hidden_states (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, hidden_size)`): + Stacked intermediate hidden states (output of each layer of the decoder). + intermediate_logits (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, sequence_length, config.num_labels)`): + Stacked intermediate logits (logits of each layer of the decoder). + intermediate_reference_points (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, 4)`): + Stacked intermediate reference points (reference points of each layer of the decoder). + intermediate_predicted_corners (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, 4)`): + Stacked intermediate predicted corners (predicted corners of each layer of the decoder). + initial_reference_points (`torch.FloatTensor` of shape `(batch_size, num_queries, 4)`): + Initial reference points used for the first decoder layer. + init_reference_points (`torch.FloatTensor` of shape `(batch_size, num_queries, 4)`): + Initial reference points sent through the Transformer decoder. + enc_topk_logits (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.num_labels)`): + Predicted bounding boxes scores where the top `config.two_stage_num_proposals` scoring bounding boxes are + picked as region proposals in the encoder stage. Output of bounding box binary classification (i.e. + foreground and background). + enc_topk_bboxes (`torch.FloatTensor` of shape `(batch_size, sequence_length, 4)`): + Logits of predicted bounding boxes coordinates in the encoder stage. + enc_outputs_class (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.num_labels)`, *optional*, returned when `config.with_box_refine=True` and `config.two_stage=True`): + Predicted bounding boxes scores where the top `config.two_stage_num_proposals` scoring bounding boxes are + picked as region proposals in the first stage. Output of bounding box binary classification (i.e. + foreground and background). + enc_outputs_coord_logits (`torch.FloatTensor` of shape `(batch_size, sequence_length, 4)`, *optional*, returned when `config.with_box_refine=True` and `config.two_stage=True`): + Logits of predicted bounding boxes coordinates in the first stage. + denoising_meta_values (`dict`): + Extra dictionary for the denoising related values. + """ + + last_hidden_state: torch.FloatTensor | None = None + intermediate_hidden_states: torch.FloatTensor | None = None + intermediate_logits: torch.FloatTensor | None = None + intermediate_reference_points: torch.FloatTensor | None = None + intermediate_predicted_corners: torch.FloatTensor | None = None + initial_reference_points: torch.FloatTensor | None = None + decoder_hidden_states: tuple[torch.FloatTensor] | None = None + decoder_attentions: tuple[torch.FloatTensor] | None = None + cross_attentions: tuple[torch.FloatTensor] | None = None + encoder_last_hidden_state: torch.FloatTensor | None = None + encoder_hidden_states: tuple[torch.FloatTensor] | None = None + encoder_attentions: tuple[torch.FloatTensor] | None = None + init_reference_points: torch.FloatTensor | None = None + enc_topk_logits: torch.FloatTensor | None = None + enc_topk_bboxes: torch.FloatTensor | None = None + enc_outputs_class: torch.FloatTensor | None = None + enc_outputs_coord_logits: torch.FloatTensor | None = None + denoising_meta_values: dict | None = None + + +@dataclass +@auto_docstring( + custom_intro=""" + Output type of [`RTDetrForObjectDetection`]. + """ +) +class RTDetrObjectDetectionOutput(ModelOutput): + r""" + loss (`torch.FloatTensor` of shape `(1,)`, *optional*, returned when `labels` are provided)): + Total loss as a linear combination of a negative log-likehood (cross-entropy) for class prediction and a + bounding box loss. The latter is defined as a linear combination of the L1 loss and the generalized + scale-invariant IoU loss. + loss_dict (`Dict`, *optional*): + A dictionary containing the individual losses. Useful for logging. + logits (`torch.FloatTensor` of shape `(batch_size, num_queries, num_classes + 1)`): + Classification logits (including no-object) for all queries. + pred_boxes (`torch.FloatTensor` of shape `(batch_size, num_queries, 4)`): + Normalized boxes coordinates for all queries, represented as (center_x, center_y, width, height). These + values are normalized in [0, 1], relative to the size of each individual image in the batch (disregarding + possible padding). You can use [`~RTDetrImageProcessor.post_process_object_detection`] to retrieve the + unnormalized (absolute) bounding boxes. + auxiliary_outputs (`list[Dict]`, *optional*): + Optional, only returned when auxiliary losses are activated (i.e. `config.auxiliary_loss` is set to `True`) + and labels are provided. It is a list of dictionaries containing the two above keys (`logits` and + `pred_boxes`) for each decoder layer. + last_hidden_state (`torch.FloatTensor` of shape `(batch_size, num_queries, hidden_size)`): + Sequence of hidden-states at the output of the last layer of the decoder of the model. + intermediate_hidden_states (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, hidden_size)`): + Stacked intermediate hidden states (output of each layer of the decoder). + intermediate_logits (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, config.num_labels)`): + Stacked intermediate logits (logits of each layer of the decoder). + intermediate_reference_points (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, 4)`): + Stacked intermediate reference points (reference points of each layer of the decoder). + intermediate_predicted_corners (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, 4)`): + Stacked intermediate predicted corners (predicted corners of each layer of the decoder). + initial_reference_points (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, 4)`): + Stacked initial reference points (initial reference points of each layer of the decoder). + init_reference_points (`torch.FloatTensor` of shape `(batch_size, num_queries, 4)`): + Initial reference points sent through the Transformer decoder. + enc_topk_logits (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.num_labels)`, *optional*, returned when `config.with_box_refine=True` and `config.two_stage=True`): + Logits of predicted bounding boxes coordinates in the encoder. + enc_topk_bboxes (`torch.FloatTensor` of shape `(batch_size, sequence_length, 4)`, *optional*, returned when `config.with_box_refine=True` and `config.two_stage=True`): + Logits of predicted bounding boxes coordinates in the encoder. + enc_outputs_class (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.num_labels)`, *optional*, returned when `config.with_box_refine=True` and `config.two_stage=True`): + Predicted bounding boxes scores where the top `config.two_stage_num_proposals` scoring bounding boxes are + picked as region proposals in the first stage. Output of bounding box binary classification (i.e. + foreground and background). + enc_outputs_coord_logits (`torch.FloatTensor` of shape `(batch_size, sequence_length, 4)`, *optional*, returned when `config.with_box_refine=True` and `config.two_stage=True`): + Logits of predicted bounding boxes coordinates in the first stage. + denoising_meta_values (`dict`): + Extra dictionary for the denoising related values + """ + + loss: torch.FloatTensor | None = None + loss_dict: dict | None = None + logits: torch.FloatTensor | None = None + pred_boxes: torch.FloatTensor | None = None + auxiliary_outputs: list[dict] | None = None + last_hidden_state: torch.FloatTensor | None = None + intermediate_hidden_states: torch.FloatTensor | None = None + intermediate_logits: torch.FloatTensor | None = None + intermediate_reference_points: torch.FloatTensor | None = None + intermediate_predicted_corners: torch.FloatTensor | None = None + initial_reference_points: torch.FloatTensor | None = None + decoder_hidden_states: tuple[torch.FloatTensor] | None = None + decoder_attentions: tuple[torch.FloatTensor] | None = None + cross_attentions: tuple[torch.FloatTensor] | None = None + encoder_last_hidden_state: torch.FloatTensor | None = None + encoder_hidden_states: tuple[torch.FloatTensor] | None = None + encoder_attentions: tuple[torch.FloatTensor] | None = None + init_reference_points: tuple[torch.FloatTensor] | None = None + enc_topk_logits: torch.FloatTensor | None = None + enc_topk_bboxes: torch.FloatTensor | None = None + enc_outputs_class: torch.FloatTensor | None = None + enc_outputs_coord_logits: torch.FloatTensor | None = None + denoising_meta_values: dict | None = None + + +class RTDetrMLP(nn.Module): + def __init__(self, config: RTDetrConfig, hidden_size: int, intermediate_size: int, activation_function: str): + super().__init__() + self.fc1 = nn.Linear(hidden_size, intermediate_size) + self.fc2 = nn.Linear(intermediate_size, hidden_size) + self.activation_fn = ACT2FN[activation_function] + self.activation_dropout = config.activation_dropout + self.dropout = config.dropout + + def forward(self, hidden_states: torch.Tensor) -> torch.Tensor: + hidden_states = self.activation_fn(self.fc1(hidden_states)) + hidden_states = nn.functional.dropout(hidden_states, p=self.activation_dropout, training=self.training) + hidden_states = self.fc2(hidden_states) + hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training) + return hidden_states + + +class RTDetrFrozenBatchNorm2d(DetrFrozenBatchNorm2d): + pass + + +class RTDetrSelfAttention(DetrSelfAttention): + pass + + +def get_contrastive_denoising_training_group( + targets, + num_classes, + num_queries, + class_embed, + num_denoising_queries=100, + label_noise_ratio=0.5, + box_noise_scale=1.0, +): + """ + Creates a contrastive denoising training group using ground-truth samples. It adds noise to labels and boxes. + + Args: + targets (`list[dict]`): + The target objects, each containing 'class_labels' and 'boxes' for objects in an image. + num_classes (`int`): + Total number of classes in the dataset. + num_queries (`int`): + Number of query slots in the transformer. + class_embed (`callable`): + A function or a model layer to embed class labels. + num_denoising_queries (`int`, *optional*, defaults to 100): + Number of denoising queries. + label_noise_ratio (`float`, *optional*, defaults to 0.5): + Ratio of noise applied to labels. + box_noise_scale (`float`, *optional*, defaults to 1.0): + Scale of noise applied to bounding boxes. + Returns: + `tuple` comprising various elements: + - **input_query_class** (`torch.FloatTensor`) -- + Class queries with applied label noise. + - **input_query_bbox** (`torch.FloatTensor`) -- + Bounding box queries with applied box noise. + - **attn_mask** (`torch.FloatTensor`) -- + Attention mask for separating denoising and reconstruction queries. + - **denoising_meta_values** (`dict`) -- + Metadata including denoising positive indices, number of groups, and split sizes. + """ + + if num_denoising_queries <= 0: + return None, None, None, None + + num_ground_truths = [len(t["class_labels"]) for t in targets] + device = targets[0]["class_labels"].device + + max_gt_num = max(num_ground_truths) + if max_gt_num == 0: + return None, None, None, None + + num_groups_denoising_queries = num_denoising_queries // max_gt_num + num_groups_denoising_queries = 1 if num_groups_denoising_queries == 0 else num_groups_denoising_queries + # pad gt to max_num of a batch + batch_size = len(num_ground_truths) + + input_query_class = torch.full([batch_size, max_gt_num], num_classes, dtype=torch.int32, device=device) + input_query_bbox = torch.zeros([batch_size, max_gt_num, 4], device=device) + pad_gt_mask = torch.zeros([batch_size, max_gt_num], dtype=torch.bool, device=device) + + for i in range(batch_size): + num_gt = num_ground_truths[i] + if num_gt > 0: + input_query_class[i, :num_gt] = targets[i]["class_labels"] + input_query_bbox[i, :num_gt] = targets[i]["boxes"] + pad_gt_mask[i, :num_gt] = 1 + # each group has positive and negative queries. + input_query_class = input_query_class.tile([1, 2 * num_groups_denoising_queries]) + input_query_bbox = input_query_bbox.tile([1, 2 * num_groups_denoising_queries, 1]) + pad_gt_mask = pad_gt_mask.tile([1, 2 * num_groups_denoising_queries]) + # positive and negative mask + negative_gt_mask = torch.zeros([batch_size, max_gt_num * 2, 1], device=device) + negative_gt_mask[:, max_gt_num:] = 1 + negative_gt_mask = negative_gt_mask.tile([1, num_groups_denoising_queries, 1]) + positive_gt_mask = 1 - negative_gt_mask + # contrastive denoising training positive index + positive_gt_mask = positive_gt_mask.squeeze(-1) * pad_gt_mask + denoise_positive_idx = torch.nonzero(positive_gt_mask)[:, 1] + denoise_positive_idx = torch.split( + denoise_positive_idx, [n * num_groups_denoising_queries for n in num_ground_truths] + ) + # total denoising queries + num_denoising_queries = torch_int(max_gt_num * 2 * num_groups_denoising_queries) + + if label_noise_ratio > 0: + mask = torch.rand_like(input_query_class, dtype=torch.float) < (label_noise_ratio * 0.5) + # randomly put a new one here + new_label = torch.randint_like(mask, 0, num_classes, dtype=input_query_class.dtype) + input_query_class = torch.where(mask & pad_gt_mask, new_label, input_query_class) + + if box_noise_scale > 0: + known_bbox = center_to_corners_format(input_query_bbox) + diff = torch.tile(input_query_bbox[..., 2:] * 0.5, [1, 1, 2]) * box_noise_scale + rand_sign = torch.randint_like(input_query_bbox, 0, 2) * 2.0 - 1.0 + rand_part = torch.rand_like(input_query_bbox) + rand_part = (rand_part + 1.0) * negative_gt_mask + rand_part * (1 - negative_gt_mask) + rand_part *= rand_sign + known_bbox += rand_part * diff + known_bbox.clip_(min=0.0, max=1.0) + input_query_bbox = corners_to_center_format(known_bbox) + input_query_bbox = inverse_sigmoid(input_query_bbox) + + input_query_class = class_embed(input_query_class) + + target_size = num_denoising_queries + num_queries + attn_mask = torch.full([target_size, target_size], 0, dtype=torch.float, device=device) + # match query cannot see the reconstruction + attn_mask[num_denoising_queries:, :num_denoising_queries] = -torch.inf + + # reconstructions cannot see each other + for i in range(num_groups_denoising_queries): + idx_block_start = max_gt_num * 2 * i + idx_block_end = max_gt_num * 2 * (i + 1) + attn_mask[idx_block_start:idx_block_end, :idx_block_start] = -torch.inf + attn_mask[idx_block_start:idx_block_end, idx_block_end:num_denoising_queries] = -torch.inf + + denoising_meta_values = { + "dn_positive_idx": denoise_positive_idx, + "dn_num_group": num_groups_denoising_queries, + "dn_num_split": [num_denoising_queries, num_queries], + } + + return input_query_class, input_query_bbox, attn_mask, denoising_meta_values + + +class RTDetrConvEncoder(nn.Module): + """ + Convolutional backbone using the modeling_rt_detr_resnet.py. + + nn.BatchNorm2d layers are replaced by RTDetrFrozenBatchNorm2d as defined above. + https://github.com/lyuwenyu/RT-DETR/blob/main/rtdetr_pytorch/src/nn/backbone/presnet.py#L142 + """ + + def __init__(self, config): + super().__init__() + + backbone = load_backbone(config) + + if config.freeze_backbone_batch_norms: + # replace batch norm by frozen batch norm + with torch.no_grad(): + replace_batch_norm(backbone) + self.model = backbone + self.intermediate_channel_sizes = self.model.channels + + def forward(self, pixel_values: torch.Tensor, pixel_mask: torch.Tensor): + # send pixel_values through the model to get list of feature maps + features = self.model(pixel_values).feature_maps + + out = [] + for feature_map in features: + # downsample pixel_mask to match shape of corresponding feature_map + mask = nn.functional.interpolate(pixel_mask[None].float(), size=feature_map.shape[-2:]).to(torch.bool)[0] + out.append((feature_map, mask)) + return out + + +class RTDetrConvNormLayer(nn.Module): + def __init__(self, config, in_channels, out_channels, kernel_size, stride, padding=None, activation=None): + super().__init__() + self.conv = nn.Conv2d( + in_channels, + out_channels, + kernel_size, + stride, + padding=(kernel_size - 1) // 2 if padding is None else padding, + bias=False, + ) + self.norm = nn.BatchNorm2d(out_channels, config.batch_norm_eps) + self.activation = nn.Identity() if activation is None else ACT2CLS[activation]() + + def forward(self, hidden_state): + hidden_state = self.conv(hidden_state) + hidden_state = self.norm(hidden_state) + hidden_state = self.activation(hidden_state) + return hidden_state + + +class RTDetrEncoderLayer(nn.Module): + def __init__(self, config: RTDetrConfig): + super().__init__() + self.normalize_before = config.normalize_before + self.hidden_size = config.encoder_hidden_dim + + # self-attention + self.self_attn = RTDetrSelfAttention( + config=config, + hidden_size=self.hidden_size, + num_attention_heads=config.num_attention_heads, + dropout=config.dropout, + ) + self.self_attn_layer_norm = nn.LayerNorm(self.hidden_size, eps=config.layer_norm_eps) + self.dropout = config.dropout + self.mlp = RTDetrMLP(config, self.hidden_size, config.encoder_ffn_dim, config.encoder_activation_function) + self.final_layer_norm = nn.LayerNorm(self.hidden_size, eps=config.layer_norm_eps) + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.Tensor, + spatial_position_embeddings: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> torch.Tensor: + """ + Args: + hidden_states (`torch.FloatTensor`): input to the layer of shape `(batch, seq_len, hidden_size)` + attention_mask (`torch.FloatTensor`): attention mask of size + `(batch, 1, target_len, source_len)` where padding elements are indicated by very large negative + values. + spatial_position_embeddings (`torch.FloatTensor`, *optional*): + Spatial position embeddings (2D positional encodings of image locations), to be added to both + the queries and keys in self-attention (but not to values). + """ + residual = hidden_states + if self.normalize_before: + hidden_states = self.self_attn_layer_norm(hidden_states) + + hidden_states, _ = self.self_attn( + hidden_states=hidden_states, + attention_mask=attention_mask, + position_embeddings=spatial_position_embeddings, + **kwargs, + ) + + hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training) + hidden_states = residual + hidden_states + if not self.normalize_before: + hidden_states = self.self_attn_layer_norm(hidden_states) + + if self.normalize_before: + hidden_states = self.final_layer_norm(hidden_states) + residual = hidden_states + + hidden_states = self.mlp(hidden_states) + + hidden_states = residual + hidden_states + if not self.normalize_before: + hidden_states = self.final_layer_norm(hidden_states) + + if self.training: + if not torch.isfinite(hidden_states).all(): + clamp_value = torch.finfo(hidden_states.dtype).max - 1000 + hidden_states = torch.clamp(hidden_states, min=-clamp_value, max=clamp_value) + + return hidden_states + + +class RTDetrRepVggBlock(nn.Module): + """ + RepVGG architecture block introduced by the work "RepVGG: Making VGG-style ConvNets Great Again". + """ + + def __init__(self, config: RTDetrConfig): + super().__init__() + + activation = config.activation_function + hidden_channels = int(config.encoder_hidden_dim * config.hidden_expansion) + self.conv1 = RTDetrConvNormLayer(config, hidden_channels, hidden_channels, 3, 1, padding=1) + self.conv2 = RTDetrConvNormLayer(config, hidden_channels, hidden_channels, 1, 1, padding=0) + self.activation = nn.Identity() if activation is None else ACT2CLS[activation]() + + def forward(self, x): + y = self.conv1(x) + self.conv2(x) + return self.activation(y) + + +class RTDetrCSPRepLayer(nn.Module): + """ + Cross Stage Partial (CSP) network layer with RepVGG blocks. + """ + + def __init__(self, config: RTDetrConfig): + super().__init__() + + in_channels = config.encoder_hidden_dim * 2 + out_channels = config.encoder_hidden_dim + num_blocks = 3 + activation = config.activation_function + + hidden_channels = int(out_channels * config.hidden_expansion) + self.conv1 = RTDetrConvNormLayer(config, in_channels, hidden_channels, 1, 1, activation=activation) + self.conv2 = RTDetrConvNormLayer(config, in_channels, hidden_channels, 1, 1, activation=activation) + self.bottlenecks = nn.Sequential(*[RTDetrRepVggBlock(config) for _ in range(num_blocks)]) + if hidden_channels != out_channels: + self.conv3 = RTDetrConvNormLayer(config, hidden_channels, out_channels, 1, 1, activation=activation) + else: + self.conv3 = nn.Identity() + + def forward(self, hidden_state): + hidden_state_1 = self.conv1(hidden_state) + hidden_state_1 = self.bottlenecks(hidden_state_1) + hidden_state_2 = self.conv2(hidden_state) + return self.conv3(hidden_state_1 + hidden_state_2) + + +class RTDetrMultiscaleDeformableAttention(DeformableDetrMultiscaleDeformableAttention): + pass + + +class RTDetrDecoderLayer(nn.Module): + def __init__(self, config: RTDetrConfig): + super().__init__() + self.hidden_size = config.d_model + + # self-attention + self.self_attn = RTDetrSelfAttention( + config=config, + hidden_size=self.hidden_size, + num_attention_heads=config.decoder_attention_heads, + dropout=config.attention_dropout, + ) + self.dropout = config.dropout + + self.self_attn_layer_norm = nn.LayerNorm(self.hidden_size, eps=config.layer_norm_eps) + # cross-attention + self.encoder_attn = RTDetrMultiscaleDeformableAttention( + config, + num_heads=config.decoder_attention_heads, + n_points=config.decoder_n_points, + ) + self.encoder_attn_layer_norm = nn.LayerNorm(self.hidden_size, eps=config.layer_norm_eps) + # feedforward neural networks + self.mlp = RTDetrMLP(config, self.hidden_size, config.decoder_ffn_dim, config.decoder_activation_function) + self.final_layer_norm = nn.LayerNorm(self.hidden_size, eps=config.layer_norm_eps) + + def forward( + self, + hidden_states: torch.Tensor, + object_queries_position_embeddings: torch.Tensor | None = None, + reference_points=None, + spatial_shapes=None, + spatial_shapes_list=None, + level_start_index=None, + encoder_hidden_states: torch.Tensor | None = None, + encoder_attention_mask: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> torch.Tensor: + """ + Args: + hidden_states (`torch.FloatTensor`): + Input to the layer of shape `(batch, seq_len, hidden_size)`. + object_queries_position_embeddings (`torch.FloatTensor`, *optional*): + Position embeddings for the object query slots. These are added to both queries and keys + in the self-attention layer (not values). + reference_points (`torch.FloatTensor`, *optional*): + Reference points. + spatial_shapes (`torch.LongTensor`, *optional*): + Spatial shapes. + level_start_index (`torch.LongTensor`, *optional*): + Level start index. + encoder_hidden_states (`torch.FloatTensor`): + cross attention input to the layer of shape `(batch, seq_len, hidden_size)` + encoder_attention_mask (`torch.FloatTensor`): encoder attention mask of size + `(batch, 1, target_len, source_len)` where padding elements are indicated by very large negative + values. + """ + residual = hidden_states + + # Self Attention + hidden_states, _ = self.self_attn( + hidden_states=hidden_states, + attention_mask=encoder_attention_mask, + position_embeddings=object_queries_position_embeddings, + **kwargs, + ) + + hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training) + hidden_states = residual + hidden_states + hidden_states = self.self_attn_layer_norm(hidden_states) + + residual = hidden_states + + # Cross-Attention + hidden_states, _ = self.encoder_attn( + hidden_states=hidden_states, + encoder_hidden_states=encoder_hidden_states, + position_embeddings=object_queries_position_embeddings, + reference_points=reference_points, + spatial_shapes=spatial_shapes, + spatial_shapes_list=spatial_shapes_list, + level_start_index=level_start_index, + **kwargs, + ) + + hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training) + hidden_states = residual + hidden_states + + hidden_states = self.encoder_attn_layer_norm(hidden_states) + + # Fully Connected + residual = hidden_states + hidden_states = self.mlp(hidden_states) + hidden_states = residual + hidden_states + hidden_states = self.final_layer_norm(hidden_states) + + return hidden_states + + +class RTDetrSinePositionEmbedding(nn.Module): + """ + 2D sinusoidal position embedding used in RT-DETR hybrid encoder. + """ + + def __init__(self, embed_dim: int = 256, temperature: int = 10000): + super().__init__() + self.embed_dim = embed_dim + self.temperature = temperature + + @compile_compatible_method_lru_cache(maxsize=32) + def forward( + self, + width: int, + height: int, + device: torch.device | str, + dtype: torch.dtype, + ) -> torch.Tensor: + """ + Generate 2D sinusoidal position embeddings. + + Returns: + Position embeddings of shape (1, height*width, embed_dim) + """ + grid_w = torch.arange(torch_int(width), device=device).to(dtype) + grid_h = torch.arange(torch_int(height), device=device).to(dtype) + grid_w, grid_h = torch.meshgrid(grid_w, grid_h, indexing="xy") + if self.embed_dim % 4 != 0: + raise ValueError("Embed dimension must be divisible by 4 for 2D sin-cos position embedding") + pos_dim = self.embed_dim // 4 + omega = torch.arange(pos_dim, device=device).to(dtype) / pos_dim + omega = 1.0 / (self.temperature**omega) + + out_w = grid_w.flatten()[..., None] @ omega[None] + out_h = grid_h.flatten()[..., None] @ omega[None] + + return torch.concat([out_h.sin(), out_h.cos(), out_w.sin(), out_w.cos()], dim=1)[None, :, :] + + +class RTDetrAIFILayer(nn.Module): + """ + AIFI (Attention-based Intra-scale Feature Interaction) layer used in RT-DETR hybrid encoder. + """ + + def __init__(self, config: RTDetrConfig): + super().__init__() + self.config = config + self.encoder_hidden_dim = config.encoder_hidden_dim + self.eval_size = config.eval_size + + self.position_embedding = RTDetrSinePositionEmbedding( + embed_dim=self.encoder_hidden_dim, + temperature=config.positional_encoding_temperature, + ) + self.layers = nn.ModuleList([RTDetrEncoderLayer(config) for _ in range(config.encoder_layers)]) + + def forward( + self, + hidden_states: torch.Tensor, + **kwargs: Unpack[TransformersKwargs], + ) -> torch.Tensor: + """ + Args: + hidden_states (`torch.FloatTensor` of shape `(batch_size, channels, height, width)`): + Feature map to process. + """ + batch_size = hidden_states.shape[0] + height, width = hidden_states.shape[2:] + + hidden_states = hidden_states.flatten(2).permute(0, 2, 1) + + if self.training or self.eval_size is None: + pos_embed = self.position_embedding( + width=width, + height=height, + device=hidden_states.device, + dtype=hidden_states.dtype, + ) + else: + pos_embed = None + + for layer in self.layers: + hidden_states = layer( + hidden_states, + attention_mask=None, + spatial_position_embeddings=pos_embed, + **kwargs, + ) + + hidden_states = ( + hidden_states.permute(0, 2, 1).reshape(batch_size, self.encoder_hidden_dim, height, width).contiguous() + ) + + return hidden_states + + +class RTDetrMLPPredictionHead(DetrMLPPredictionHead): + pass + + +@auto_docstring +class RTDetrPreTrainedModel(PreTrainedModel): + config: RTDetrConfig + base_model_prefix = "rt_detr" + main_input_name = "pixel_values" + input_modalities = ("image",) + _no_split_modules = [r"RTDetrHybridEncoder", r"RTDetrDecoderLayer"] + _supports_sdpa = True + _supports_flash_attn = True + _supports_attention_backend = True + _supports_flex_attn = True + + @torch.no_grad() + def _init_weights(self, module): + """Initialize the weights""" + if isinstance(module, RTDetrForObjectDetection): + if module.model.decoder.class_embed is not None: + for layer in module.model.decoder.class_embed: + prior_prob = self.config.initializer_bias_prior_prob or 1 / (self.config.num_labels + 1) + bias = float(-math.log((1 - prior_prob) / prior_prob)) + init.xavier_uniform_(layer.weight) + init.constant_(layer.bias, bias) + + if module.model.decoder.bbox_embed is not None: + for layer in module.model.decoder.bbox_embed: + init.constant_(layer.layers[-1].weight, 0) + init.constant_(layer.layers[-1].bias, 0) + + elif isinstance(module, RTDetrMultiscaleDeformableAttention): + init.constant_(module.sampling_offsets.weight, 0.0) + default_dtype = torch.get_default_dtype() + thetas = torch.arange(module.n_heads, dtype=torch.int64).to(default_dtype) * ( + 2.0 * math.pi / module.n_heads + ) + grid_init = torch.stack([thetas.cos(), thetas.sin()], -1) + grid_init = ( + (grid_init / grid_init.abs().max(-1, keepdim=True)[0]) + .view(module.n_heads, 1, 1, 2) + .repeat(1, module.n_levels, module.n_points, 1) + ) + for i in range(module.n_points): + grid_init[:, :, i, :] *= i + 1 + + init.copy_(module.sampling_offsets.bias, grid_init.view(-1)) + init.constant_(module.attention_weights.weight, 0.0) + init.constant_(module.attention_weights.bias, 0.0) + init.xavier_uniform_(module.value_proj.weight) + init.constant_(module.value_proj.bias, 0.0) + init.xavier_uniform_(module.output_proj.weight) + init.constant_(module.output_proj.bias, 0.0) + + elif isinstance(module, RTDetrModel): + prior_prob = self.config.initializer_bias_prior_prob or 1 / (self.config.num_labels + 1) + bias = float(-math.log((1 - prior_prob) / prior_prob)) + init.xavier_uniform_(module.enc_score_head.weight) + init.constant_(module.enc_score_head.bias, bias) + + elif isinstance(module, (nn.Linear, nn.Conv2d, nn.BatchNorm2d)): + init.normal_(module.weight, mean=0.0, std=self.config.initializer_range) + if module.bias is not None: + init.zeros_(module.bias) + if getattr(module, "running_mean", None) is not None: + init.zeros_(module.running_mean) + init.ones_(module.running_var) + init.zeros_(module.num_batches_tracked) + + elif isinstance(module, nn.LayerNorm): + init.ones_(module.weight) + init.zeros_(module.bias) + + if hasattr(module, "weight_embedding") and self.config.learn_initial_query: + init.xavier_uniform_(module.weight_embedding.weight) + if hasattr(module, "denoising_class_embed") and self.config.num_denoising > 0: + init.xavier_uniform_(module.denoising_class_embed.weight) + + +class RTDetrHybridEncoder(RTDetrPreTrainedModel): + """ + Hybrid encoder consisting of AIFI (Attention-based Intra-scale Feature Interaction) layers, + a top-down Feature Pyramid Network (FPN) and a bottom-up Path Aggregation Network (PAN). + More details on the paper: https://huggingface.co/papers/2304.08069 + + Args: + config: RTDetrConfig + """ + + _can_record_outputs = { + "hidden_states": RTDetrAIFILayer, + "attentions": RTDetrSelfAttention, + } + + def __init__(self, config: RTDetrConfig): + super().__init__(config) + self.config = config + self.in_channels = config.encoder_in_channels + self.feat_strides = config.feat_strides + self.encoder_hidden_dim = config.encoder_hidden_dim + self.encode_proj_layers = config.encode_proj_layers + self.positional_encoding_temperature = config.positional_encoding_temperature + self.eval_size = config.eval_size + self.out_channels = [self.encoder_hidden_dim for _ in self.in_channels] + self.out_strides = self.feat_strides + self.num_fpn_stages = len(self.in_channels) - 1 + self.num_pan_stages = len(self.in_channels) - 1 + + # AIFI (Attention-based Intra-scale Feature Interaction) layers + self.aifi = nn.ModuleList([RTDetrAIFILayer(config) for _ in range(len(self.encode_proj_layers))]) + + # top-down FPN + self.lateral_convs = nn.ModuleList() + self.fpn_blocks = nn.ModuleList() + for _ in range(self.num_fpn_stages): + lateral_conv = RTDetrConvNormLayer( + config, + in_channels=self.encoder_hidden_dim, + out_channels=self.encoder_hidden_dim, + kernel_size=1, + stride=1, + activation=config.activation_function, + ) + fpn_block = RTDetrCSPRepLayer(config) + self.lateral_convs.append(lateral_conv) + self.fpn_blocks.append(fpn_block) + + # bottom-up PAN + self.downsample_convs = nn.ModuleList() + self.pan_blocks = nn.ModuleList() + for _ in range(self.num_pan_stages): + downsample_conv = RTDetrConvNormLayer( + config, + in_channels=self.encoder_hidden_dim, + out_channels=self.encoder_hidden_dim, + kernel_size=3, + stride=2, + activation=config.activation_function, + ) + pan_block = RTDetrCSPRepLayer(config) + self.downsample_convs.append(downsample_conv) + self.pan_blocks.append(pan_block) + + self.post_init() + + @merge_with_config_defaults + @capture_outputs(tie_last_hidden_states=False) + def forward( + self, + inputs_embeds=None, + **kwargs: Unpack[TransformersKwargs], + ) -> BaseModelOutput: + r""" + Args: + inputs_embeds (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`): + Flattened feature map (output of the backbone + projection layer) that is passed to the encoder. + """ + feature_maps = inputs_embeds + + # AIFI: Apply transformer encoder to specified feature levels + if self.config.encoder_layers > 0: + for i, enc_ind in enumerate(self.encode_proj_layers): + feature_maps[enc_ind] = self.aifi[i](feature_maps[enc_ind], **kwargs) + + # top-down FPN + fpn_feature_maps = [feature_maps[-1]] + for idx, (lateral_conv, fpn_block) in enumerate(zip(self.lateral_convs, self.fpn_blocks)): + backbone_feature_map = feature_maps[self.num_fpn_stages - idx - 1] + top_fpn_feature_map = fpn_feature_maps[-1] + # apply lateral block + top_fpn_feature_map = lateral_conv(top_fpn_feature_map) + fpn_feature_maps[-1] = top_fpn_feature_map + # apply fpn block + top_fpn_feature_map = F.interpolate(top_fpn_feature_map, scale_factor=2.0, mode="nearest") + fused_feature_map = torch.concat([top_fpn_feature_map, backbone_feature_map], dim=1) + new_fpn_feature_map = fpn_block(fused_feature_map) + fpn_feature_maps.append(new_fpn_feature_map) + + fpn_feature_maps.reverse() + + # bottom-up PAN + pan_feature_maps = [fpn_feature_maps[0]] + for idx, (downsample_conv, pan_block) in enumerate(zip(self.downsample_convs, self.pan_blocks)): + top_pan_feature_map = pan_feature_maps[-1] + fpn_feature_map = fpn_feature_maps[idx + 1] + downsampled_feature_map = downsample_conv(top_pan_feature_map) + fused_feature_map = torch.concat([downsampled_feature_map, fpn_feature_map], dim=1) + new_pan_feature_map = pan_block(fused_feature_map) + pan_feature_maps.append(new_pan_feature_map) + + return BaseModelOutput(last_hidden_state=pan_feature_maps) + + +class RTDetrDecoder(RTDetrPreTrainedModel): + _can_record_outputs = { + "hidden_states": RTDetrDecoderLayer, + "attentions": RTDetrSelfAttention, + "cross_attentions": RTDetrMultiscaleDeformableAttention, + } + + def __init__(self, config: RTDetrConfig): + super().__init__(config) + + self.dropout = config.dropout + self.layers = nn.ModuleList([RTDetrDecoderLayer(config) for _ in range(config.decoder_layers)]) + self.query_pos_head = RTDetrMLPPredictionHead(4, 2 * config.d_model, config.d_model, num_layers=2) + + # hack implementation for iterative bounding box refinement and two-stage Deformable DETR + self.bbox_embed = None + self.class_embed = None + + # Initialize weights and apply final processing + self.post_init() + + @merge_with_config_defaults + @capture_outputs + def forward( + self, + inputs_embeds=None, + encoder_hidden_states=None, + encoder_attention_mask=None, + reference_points=None, + spatial_shapes=None, + spatial_shapes_list=None, + level_start_index=None, + **kwargs: Unpack[TransformersKwargs], + ): + r""" + Args: + inputs_embeds (`torch.FloatTensor` of shape `(batch_size, num_queries, hidden_size)`): + The query embeddings that are passed into the decoder. + encoder_hidden_states (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*): + Sequence of hidden-states at the output of the last layer of the encoder. Used in the cross-attention + of the decoder. + encoder_attention_mask (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Mask to avoid performing cross-attention on padding pixel_values of the encoder. Mask values selected + in `[0, 1]`: + - 1 for pixels that are real (i.e. **not masked**), + - 0 for pixels that are padding (i.e. **masked**). + reference_points (`torch.FloatTensor` of shape `(batch_size, num_queries, 4)` is `as_two_stage` else `(batch_size, num_queries, 2)` or , *optional*): + Reference point in range `[0, 1]`, top-left (0,0), bottom-right (1, 1), including padding area. + spatial_shapes (`torch.FloatTensor` of shape `(num_feature_levels, 2)`): + Spatial shapes of the feature maps. + level_start_index (`torch.LongTensor` of shape `(num_feature_levels)`, *optional*): + Indexes for the start of each feature level. In range `[0, sequence_length]`. + """ + if inputs_embeds is not None: + hidden_states = inputs_embeds + + # decoder layers + intermediate = () + intermediate_reference_points = () + intermediate_logits = () + + reference_points = F.sigmoid(reference_points) + + # https://github.com/lyuwenyu/RT-DETR/blob/94f5e16708329d2f2716426868ec89aa774af016/rtdetr_pytorch/src/zoo/rtdetr/rtdetr_decoder.py#L252 + for idx, decoder_layer in enumerate(self.layers): + reference_points_input = reference_points.unsqueeze(2) + object_queries_position_embeddings = self.query_pos_head(reference_points) + + hidden_states = decoder_layer( + hidden_states, + object_queries_position_embeddings=object_queries_position_embeddings, + encoder_hidden_states=encoder_hidden_states, + reference_points=reference_points_input, + spatial_shapes=spatial_shapes, + spatial_shapes_list=spatial_shapes_list, + level_start_index=level_start_index, + encoder_attention_mask=encoder_attention_mask, + **kwargs, + ) + + # hack implementation for iterative bounding box refinement + if self.bbox_embed is not None: + predicted_corners = self.bbox_embed[idx](hidden_states) + new_reference_points = F.sigmoid(predicted_corners + inverse_sigmoid(reference_points)) + reference_points = new_reference_points.detach() + + intermediate += (hidden_states,) + intermediate_reference_points += ( + (new_reference_points,) if self.bbox_embed is not None else (reference_points,) + ) + + if self.class_embed is not None: + logits = self.class_embed[idx](hidden_states) + intermediate_logits += (logits,) + + # Keep batch_size as first dimension + intermediate = torch.stack(intermediate, dim=1) + intermediate_reference_points = torch.stack(intermediate_reference_points, dim=1) + if self.class_embed is not None: + intermediate_logits = torch.stack(intermediate_logits, dim=1) + + return RTDetrDecoderOutput( + last_hidden_state=hidden_states, + intermediate_hidden_states=intermediate, + intermediate_logits=intermediate_logits, + intermediate_reference_points=intermediate_reference_points, + ) + + +@auto_docstring( + custom_intro=""" + RT-DETR Model (consisting of a backbone and encoder-decoder) outputting raw hidden states without any head on top. + """ +) +class RTDetrModel(RTDetrPreTrainedModel): + def __init__(self, config: RTDetrConfig): + super().__init__(config) + + # Create backbone + self.backbone = RTDetrConvEncoder(config) + intermediate_channel_sizes = self.backbone.intermediate_channel_sizes + + # Create encoder input projection layers + # https://github.com/lyuwenyu/RT-DETR/blob/94f5e16708329d2f2716426868ec89aa774af016/rtdetr_pytorch/src/zoo/rtdetr/hybrid_encoder.py#L212 + num_backbone_outs = len(intermediate_channel_sizes) + encoder_input_proj_list = [] + for i in range(num_backbone_outs): + in_channels = intermediate_channel_sizes[i] + encoder_input_proj_list.append( + nn.Sequential( + nn.Conv2d(in_channels, config.encoder_hidden_dim, kernel_size=1, bias=False), + nn.BatchNorm2d(config.encoder_hidden_dim), + ) + ) + self.encoder_input_proj = nn.ModuleList(encoder_input_proj_list) + + # Create encoder + self.encoder = RTDetrHybridEncoder(config) + + # denoising part + if config.num_denoising > 0: + self.denoising_class_embed = nn.Embedding( + config.num_labels + 1, config.d_model, padding_idx=config.num_labels + ) + + # decoder embedding + if config.learn_initial_query: + self.weight_embedding = nn.Embedding(config.num_queries, config.d_model) + + # encoder head + self.enc_output = nn.Sequential( + nn.Linear(config.d_model, config.d_model), + nn.LayerNorm(config.d_model, eps=config.layer_norm_eps), + ) + self.enc_score_head = nn.Linear(config.d_model, config.num_labels) + self.enc_bbox_head = RTDetrMLPPredictionHead(config.d_model, config.d_model, 4, num_layers=3) + + # init encoder output anchors and valid_mask + if config.anchor_image_size: + self.anchors, self.valid_mask = self.generate_anchors(dtype=self.dtype) + + # Create decoder input projection layers + # https://github.com/lyuwenyu/RT-DETR/blob/94f5e16708329d2f2716426868ec89aa774af016/rtdetr_pytorch/src/zoo/rtdetr/rtdetr_decoder.py#L412 + num_backbone_outs = len(config.decoder_in_channels) + decoder_input_proj_list = [] + for i in range(num_backbone_outs): + in_channels = config.decoder_in_channels[i] + decoder_input_proj_list.append( + nn.Sequential( + nn.Conv2d(in_channels, config.d_model, kernel_size=1, bias=False), + nn.BatchNorm2d(config.d_model, config.batch_norm_eps), + ) + ) + for _ in range(config.num_feature_levels - num_backbone_outs): + decoder_input_proj_list.append( + nn.Sequential( + nn.Conv2d(in_channels, config.d_model, kernel_size=3, stride=2, padding=1, bias=False), + nn.BatchNorm2d(config.d_model, config.batch_norm_eps), + ) + ) + in_channels = config.d_model + self.decoder_input_proj = nn.ModuleList(decoder_input_proj_list) + + # decoder + self.decoder = RTDetrDecoder(config) + + self.post_init() + + def freeze_backbone(self): + for param in self.backbone.parameters(): + param.requires_grad_(False) + + def unfreeze_backbone(self): + for param in self.backbone.parameters(): + param.requires_grad_(True) + + @compile_compatible_method_lru_cache(maxsize=32) + def generate_anchors(self, spatial_shapes=None, grid_size=0.05, device="cpu", dtype=torch.float32): + if spatial_shapes is None: + spatial_shapes = [ + [int(self.config.anchor_image_size[0] / s), int(self.config.anchor_image_size[1] / s)] + for s in self.config.feat_strides + ] + anchors = [] + for level, (height, width) in enumerate(spatial_shapes): + grid_y, grid_x = torch.meshgrid( + torch.arange(end=height, device=device).to(dtype), + torch.arange(end=width, device=device).to(dtype), + indexing="ij", + ) + grid_xy = torch.stack([grid_x, grid_y], -1) + grid_xy = grid_xy.unsqueeze(0) + 0.5 + grid_xy[..., 0] /= width + grid_xy[..., 1] /= height + wh = torch.ones_like(grid_xy) * grid_size * (2.0**level) + anchors.append(torch.concat([grid_xy, wh], -1).reshape(-1, height * width, 4)) + # define the valid range for anchor coordinates + eps = 1e-2 + anchors = torch.concat(anchors, 1) + valid_mask = ((anchors > eps) * (anchors < 1 - eps)).all(-1, keepdim=True) + anchors = torch.log(anchors / (1 - anchors)) + anchors = torch.where(valid_mask, anchors, torch.tensor(torch.finfo(dtype).max, dtype=dtype, device=device)) + + return anchors, valid_mask + + @auto_docstring + @can_return_tuple + def forward( + self, + pixel_values: torch.FloatTensor, + pixel_mask: torch.LongTensor | None = None, + encoder_outputs: torch.FloatTensor | None = None, + inputs_embeds: torch.FloatTensor | None = None, + labels: list[dict] | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.FloatTensor] | RTDetrModelOutput: + r""" + inputs_embeds (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*): + Optionally, instead of passing the flattened feature map (output of the backbone + projection layer), you + can choose to directly pass a flattened representation of an image. + labels (`list[Dict]` of len `(batch_size,)`, *optional*): + Labels for computing the bipartite matching loss. List of dicts, each dictionary containing at least the + following 2 keys: 'class_labels' and 'boxes' (the class labels and bounding boxes of an image in the batch + respectively). The class labels themselves should be a `torch.LongTensor` of len `(number of bounding boxes + in the image,)` and the boxes a `torch.FloatTensor` of shape `(number of bounding boxes in the image, 4)`. + + Examples: + + ```python + >>> from transformers import AutoImageProcessor, RTDetrModel + >>> from PIL import Image + >>> import requests + + >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg" + >>> image = Image.open(requests.get(url, stream=True).raw) + + >>> image_processor = AutoImageProcessor.from_pretrained("PekingU/rtdetr_r50vd") + >>> model = RTDetrModel.from_pretrained("PekingU/rtdetr_r50vd") + + >>> inputs = image_processor(images=image, return_tensors="pt") + + >>> outputs = model(**inputs) + + >>> last_hidden_states = outputs.last_hidden_state + >>> list(last_hidden_states.shape) + [1, 300, 256] + ```""" + if pixel_values is None and inputs_embeds is None: + raise ValueError("You have to specify either pixel_values or inputs_embeds") + + if inputs_embeds is None: + batch_size, num_channels, height, width = pixel_values.shape + device = pixel_values.device + if pixel_mask is None: + pixel_mask = torch.ones(((batch_size, height, width)), device=device) + features = self.backbone(pixel_values, pixel_mask) + proj_feats = [self.encoder_input_proj[level](source) for level, (source, mask) in enumerate(features)] + else: + batch_size = inputs_embeds.shape[0] + device = inputs_embeds.device + proj_feats = inputs_embeds + + if encoder_outputs is None: + encoder_outputs = self.encoder( + proj_feats, + **kwargs, + ) + # If the user passed a tuple for encoder_outputs, we wrap it in a BaseModelOutput + elif not isinstance(encoder_outputs, BaseModelOutput): + encoder_outputs = BaseModelOutput( + last_hidden_state=encoder_outputs[0], + hidden_states=encoder_outputs[1] if len(encoder_outputs) > 1 else None, + attentions=encoder_outputs[2] if len(encoder_outputs) > 2 else None, + ) + + # Equivalent to def _get_encoder_input + # https://github.com/lyuwenyu/RT-DETR/blob/94f5e16708329d2f2716426868ec89aa774af016/rtdetr_pytorch/src/zoo/rtdetr/rtdetr_decoder.py#L412 + sources = [] + for level, source in enumerate(encoder_outputs.last_hidden_state): + sources.append(self.decoder_input_proj[level](source)) + + # Lowest resolution feature maps are obtained via 3x3 stride 2 convolutions on the final stage + if self.config.num_feature_levels > len(sources): + _len_sources = len(sources) + sources.append(self.decoder_input_proj[_len_sources](encoder_outputs.last_hidden_state)[-1]) + for i in range(_len_sources + 1, self.config.num_feature_levels): + sources.append(self.decoder_input_proj[i](encoder_outputs.last_hidden_state[-1])) + + # Prepare encoder inputs (by flattening) + source_flatten = [] + spatial_shapes_list = [] + spatial_shapes = torch.empty((len(sources), 2), device=device, dtype=torch.long) + for level, source in enumerate(sources): + height, width = source.shape[-2:] + spatial_shapes[level, 0] = height + spatial_shapes[level, 1] = width + spatial_shapes_list.append((height, width)) + source = source.flatten(2).transpose(1, 2) + source_flatten.append(source) + source_flatten = torch.cat(source_flatten, 1) + level_start_index = torch.cat((spatial_shapes.new_zeros((1,)), spatial_shapes.prod(1).cumsum(0)[:-1])) + + # prepare denoising training + if self.training and self.config.num_denoising > 0 and labels is not None: + ( + denoising_class, + denoising_bbox_unact, + attention_mask, + denoising_meta_values, + ) = get_contrastive_denoising_training_group( + targets=labels, + num_classes=self.config.num_labels, + num_queries=self.config.num_queries, + class_embed=self.denoising_class_embed, + num_denoising_queries=self.config.num_denoising, + label_noise_ratio=self.config.label_noise_ratio, + box_noise_scale=self.config.box_noise_scale, + ) + else: + denoising_class, denoising_bbox_unact, attention_mask, denoising_meta_values = None, None, None, None + + batch_size = len(source_flatten) + device = source_flatten.device + dtype = source_flatten.dtype + + # prepare input for decoder + if self.training or self.config.anchor_image_size is None: + # Pass spatial_shapes as tuple to make it hashable and make sure + # lru_cache is working for generate_anchors() + spatial_shapes_tuple = tuple(spatial_shapes_list) + anchors, valid_mask = self.generate_anchors(spatial_shapes_tuple, device=device, dtype=dtype) + else: + anchors, valid_mask = self.anchors, self.valid_mask + anchors, valid_mask = anchors.to(device, dtype), valid_mask.to(device, dtype) + + # use the valid_mask to selectively retain values in the feature map where the mask is `True` + memory = valid_mask.to(source_flatten.dtype) * source_flatten + + output_memory = self.enc_output(memory) + + enc_outputs_class = self.enc_score_head(output_memory) + enc_outputs_coord_logits = self.enc_bbox_head(output_memory) + anchors + + _, topk_ind = torch.topk(enc_outputs_class.max(-1).values, self.config.num_queries, dim=1) + + reference_points_unact = enc_outputs_coord_logits.gather( + dim=1, index=topk_ind.unsqueeze(-1).repeat(1, 1, enc_outputs_coord_logits.shape[-1]) + ) + + enc_topk_bboxes = F.sigmoid(reference_points_unact) + if denoising_bbox_unact is not None: + reference_points_unact = torch.concat([denoising_bbox_unact, reference_points_unact], 1) + + enc_topk_logits = enc_outputs_class.gather( + dim=1, index=topk_ind.unsqueeze(-1).repeat(1, 1, enc_outputs_class.shape[-1]) + ) + + # extract region features + if self.config.learn_initial_query: + target = self.weight_embedding.tile([batch_size, 1, 1]) + else: + target = output_memory.gather(dim=1, index=topk_ind.unsqueeze(-1).repeat(1, 1, output_memory.shape[-1])) + target = target.detach() + + if denoising_class is not None: + target = torch.concat([denoising_class, target], 1) + + init_reference_points = reference_points_unact.detach() + + # decoder + decoder_outputs = self.decoder( + inputs_embeds=target, + encoder_hidden_states=source_flatten, + encoder_attention_mask=attention_mask, + reference_points=init_reference_points, + spatial_shapes=spatial_shapes, + spatial_shapes_list=spatial_shapes_list, + level_start_index=level_start_index, + **kwargs, + ) + + return RTDetrModelOutput( + last_hidden_state=decoder_outputs.last_hidden_state, + intermediate_hidden_states=decoder_outputs.intermediate_hidden_states, + intermediate_logits=decoder_outputs.intermediate_logits, + intermediate_reference_points=decoder_outputs.intermediate_reference_points, + intermediate_predicted_corners=decoder_outputs.intermediate_predicted_corners, + initial_reference_points=decoder_outputs.initial_reference_points, + decoder_hidden_states=decoder_outputs.hidden_states, + decoder_attentions=decoder_outputs.attentions, + cross_attentions=decoder_outputs.cross_attentions, + encoder_last_hidden_state=encoder_outputs.last_hidden_state, + encoder_hidden_states=encoder_outputs.hidden_states, + encoder_attentions=encoder_outputs.attentions, + init_reference_points=init_reference_points, + enc_topk_logits=enc_topk_logits, + enc_topk_bboxes=enc_topk_bboxes, + enc_outputs_class=enc_outputs_class, + enc_outputs_coord_logits=enc_outputs_coord_logits, + denoising_meta_values=denoising_meta_values, + ) + + +@auto_docstring( + custom_intro=""" + RT-DETR Model (consisting of a backbone and encoder-decoder) outputting bounding boxes and logits to be further + decoded into scores and classes. + """ +) +class RTDetrForObjectDetection(RTDetrPreTrainedModel): + # When using clones, all layers > 0 will be clones, but layer 0 *is* required + # We can't initialize the model on meta device as some weights are modified during the initialization + _no_split_modules = None + + def __init__(self, config: RTDetrConfig): + super().__init__(config) + self.model = RTDetrModel(config) + num_pred = config.decoder_layers + self.model.decoder.class_embed = nn.ModuleList( + [torch.nn.Linear(config.d_model, config.num_labels) for _ in range(num_pred)] + ) + self.model.decoder.bbox_embed = nn.ModuleList( + [RTDetrMLPPredictionHead(config.d_model, config.d_model, 4, num_layers=3) for _ in range(num_pred)] + ) + # if two-stage, the last class_embed and bbox_embed is for region proposal generation + self.post_init() + + def _set_aux_loss(self, outputs_class, outputs_coord): + return [{"logits": a, "pred_boxes": b} for a, b in zip(outputs_class, outputs_coord)] + + @auto_docstring + @can_return_tuple + def forward( + self, + pixel_values: torch.FloatTensor, + pixel_mask: torch.LongTensor | None = None, + encoder_outputs: torch.FloatTensor | None = None, + inputs_embeds: torch.FloatTensor | None = None, + labels: list[dict] | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.FloatTensor] | RTDetrObjectDetectionOutput: + r""" + inputs_embeds (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*): + Optionally, instead of passing the flattened feature map (output of the backbone + projection layer), you + can choose to directly pass a flattened representation of an image. + labels (`list[Dict]` of len `(batch_size,)`, *optional*): + Labels for computing the bipartite matching loss. List of dicts, each dictionary containing at least the + following 2 keys: 'class_labels' and 'boxes' (the class labels and bounding boxes of an image in the batch + respectively). The class labels themselves should be a `torch.LongTensor` of len `(number of bounding boxes + in the image,)` and the boxes a `torch.FloatTensor` of shape `(number of bounding boxes in the image, 4)`. + + Examples: + + ```python + >>> from transformers import RTDetrImageProcessor, RTDetrForObjectDetection + >>> from PIL import Image + >>> import requests + >>> import torch + + >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg" + >>> image = Image.open(requests.get(url, stream=True).raw) + + >>> image_processor = RTDetrImageProcessor.from_pretrained("PekingU/rtdetr_r50vd") + >>> model = RTDetrForObjectDetection.from_pretrained("PekingU/rtdetr_r50vd") + + >>> # prepare image for the model + >>> inputs = image_processor(images=image, return_tensors="pt") + + >>> # forward pass + >>> outputs = model(**inputs) + + >>> logits = outputs.logits + >>> list(logits.shape) + [1, 300, 80] + + >>> boxes = outputs.pred_boxes + >>> list(boxes.shape) + [1, 300, 4] + + >>> # convert outputs (bounding boxes and class logits) to Pascal VOC format (xmin, ymin, xmax, ymax) + >>> target_sizes = torch.tensor([image.size[::-1]]) + >>> results = image_processor.post_process_object_detection(outputs, threshold=0.9, target_sizes=target_sizes)[ + ... 0 + ... ] + + >>> for score, label, box in zip(results["scores"], results["labels"], results["boxes"]): + ... box = [round(i, 2) for i in box.tolist()] + ... print( + ... f"Detected {model.config.id2label[label.item()]} with confidence " + ... f"{round(score.item(), 3)} at location {box}" + ... ) + Detected sofa with confidence 0.97 at location [0.14, 0.38, 640.13, 476.21] + Detected cat with confidence 0.96 at location [343.38, 24.28, 640.14, 371.5] + Detected cat with confidence 0.958 at location [13.23, 54.18, 318.98, 472.22] + Detected remote with confidence 0.951 at location [40.11, 73.44, 175.96, 118.48] + Detected remote with confidence 0.924 at location [333.73, 76.58, 369.97, 186.99] + ```""" + outputs = self.model( + pixel_values, + pixel_mask=pixel_mask, + encoder_outputs=encoder_outputs, + inputs_embeds=inputs_embeds, + labels=labels, + **kwargs, + ) + + denoising_meta_values = outputs.denoising_meta_values if self.training else None + + outputs_class = outputs.intermediate_logits + outputs_coord = outputs.intermediate_reference_points + predicted_corners = outputs.intermediate_predicted_corners + initial_reference_points = outputs.initial_reference_points + + logits = outputs_class[:, -1] + pred_boxes = outputs_coord[:, -1] + + loss, loss_dict, auxiliary_outputs, enc_topk_logits, enc_topk_bboxes = None, None, None, None, None + if labels is not None: + enc_topk_logits = outputs.enc_topk_logits + enc_topk_bboxes = outputs.enc_topk_bboxes + loss, loss_dict, auxiliary_outputs = self.loss_function( + logits, + labels, + self.device, + pred_boxes, + self.config, + outputs_class, + outputs_coord, + enc_topk_logits=enc_topk_logits, + enc_topk_bboxes=enc_topk_bboxes, + denoising_meta_values=denoising_meta_values, + predicted_corners=predicted_corners, + initial_reference_points=initial_reference_points, + **kwargs, + ) + + return RTDetrObjectDetectionOutput( + loss=loss, + loss_dict=loss_dict, + logits=logits, + pred_boxes=pred_boxes, + auxiliary_outputs=auxiliary_outputs, + last_hidden_state=outputs.last_hidden_state, + intermediate_hidden_states=outputs.intermediate_hidden_states, + intermediate_logits=outputs.intermediate_logits, + intermediate_reference_points=outputs.intermediate_reference_points, + intermediate_predicted_corners=outputs.intermediate_predicted_corners, + initial_reference_points=outputs.initial_reference_points, + decoder_hidden_states=outputs.decoder_hidden_states, + decoder_attentions=outputs.decoder_attentions, + cross_attentions=outputs.cross_attentions, + encoder_last_hidden_state=outputs.encoder_last_hidden_state, + encoder_hidden_states=outputs.encoder_hidden_states, + encoder_attentions=outputs.encoder_attentions, + init_reference_points=outputs.init_reference_points, + enc_topk_logits=outputs.enc_topk_logits, + enc_topk_bboxes=outputs.enc_topk_bboxes, + enc_outputs_class=outputs.enc_outputs_class, + enc_outputs_coord_logits=outputs.enc_outputs_coord_logits, + denoising_meta_values=outputs.denoising_meta_values, + ) + + +__all__ = [ + "RTDetrImageProcessorFast", + "RTDetrForObjectDetection", + "RTDetrModel", + "RTDetrPreTrainedModel", +] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/rt_detr_v2/__init__.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/rt_detr_v2/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..efc3772ca6d015271102638c3948958777498fd9 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/rt_detr_v2/__init__.py @@ -0,0 +1,29 @@ +# Copyright 2025 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + + +from typing import TYPE_CHECKING + +from ...utils import _LazyModule +from ...utils.import_utils import define_import_structure + + +if TYPE_CHECKING: + from .configuration_rt_detr_v2 import * + from .modeling_rt_detr_v2 import * +else: + import sys + + _file = globals()["__file__"] + sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__) diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/rt_detr_v2/configuration_rt_detr_v2.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/rt_detr_v2/configuration_rt_detr_v2.py new file mode 100644 index 0000000000000000000000000000000000000000..28777c58883e034bafbb0adf32fbb199385737f8 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/rt_detr_v2/configuration_rt_detr_v2.py @@ -0,0 +1,317 @@ +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# This file was automatically generated from src/transformers/models/rt_detr_v2/modular_rt_detr_v2.py. +# Do NOT edit this file manually as any edits will be overwritten by the generation of +# the file from the modular. If any change should be done, please apply the change to the +# modular_rt_detr_v2.py file directly. One of our CI enforces this. +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# Copyright 2025 Baidu Inc and The HuggingFace Inc. team. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from ...backbone_utils import consolidate_backbone_kwargs_to_config +from ...configuration_utils import PreTrainedConfig +from ..auto import AutoConfig + + +class RTDetrV2Config(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`RTDetrV2Model`]. It is used to instantiate a + RT-DETR model according to the specified arguments, defining the model architecture. Instantiating a configuration + with the defaults will yield a similar configuration to that of the RT-DETR architecture. + + e.g. [PekingU/rtdetr_r18vd](https://huggingface.co/PekingU/rtdetr_r18vd) + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + initializer_range (`float`, *optional*, defaults to 0.01): + The standard deviation of the truncated_normal_initializer for initializing all weight matrices. + initializer_bias_prior_prob (`float`, *optional*): + The prior probability used by the bias initializer to initialize biases for `enc_score_head` and `class_embed`. + If `None`, `prior_prob` computed as `prior_prob = 1 / (num_labels + 1)` while initializing model weights. + layer_norm_eps (`float`, *optional*, defaults to 1e-05): + The epsilon used by the layer normalization layers. + batch_norm_eps (`float`, *optional*, defaults to 1e-05): + The epsilon used by the batch normalization layers. + backbone_config (`Union[dict, "PreTrainedConfig"]`, *optional*, defaults to `RTDetrV2ResNetConfig()`): + The configuration of the backbone model. + freeze_backbone_batch_norms (`bool`, *optional*, defaults to `True`): + Whether to freeze the batch normalization layers in the backbone. + encoder_hidden_dim (`int`, *optional*, defaults to 256): + Dimension of the layers in hybrid encoder. + encoder_in_channels (`list`, *optional*, defaults to `[512, 1024, 2048]`): + Multi level features input for encoder. + feat_strides (`list[int]`, *optional*, defaults to `[8, 16, 32]`): + Strides used in each feature map. + encoder_layers (`int`, *optional*, defaults to 1): + Total of layers to be used by the encoder. + encoder_ffn_dim (`int`, *optional*, defaults to 1024): + Dimension of the "intermediate" (often named feed-forward) layer in decoder. + encoder_attention_heads (`int`, *optional*, defaults to 8): + Number of attention heads for each attention layer in the Transformer encoder. + dropout (`float`, *optional*, defaults to 0.0): + The ratio for all dropout layers. + activation_dropout (`float`, *optional*, defaults to 0.0): + The dropout ratio for activations inside the fully connected layer. + encode_proj_layers (`list[int]`, *optional*, defaults to `[2]`): + Indexes of the projected layers to be used in the encoder. + positional_encoding_temperature (`int`, *optional*, defaults to 10000): + The temperature parameter used to create the positional encodings. + encoder_activation_function (`str`, *optional*, defaults to `"gelu"`): + The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`, + `"relu"`, `"silu"` and `"gelu_new"` are supported. + activation_function (`str`, *optional*, defaults to `"silu"`): + The non-linear activation function (function or string) in the general layer. If string, `"gelu"`, + `"relu"`, `"silu"` and `"gelu_new"` are supported. + eval_size (`tuple[int, int]`, *optional*): + Height and width used to compute the effective height and width of the position embeddings after taking + into account the stride. + normalize_before (`bool`, *optional*, defaults to `False`): + Determine whether to apply layer normalization in the transformer encoder layer before self-attention and + feed-forward modules. + hidden_expansion (`float`, *optional*, defaults to 1.0): + Expansion ratio to enlarge the dimension size of RepVGGBlock and CSPRepLayer. + d_model (`int`, *optional*, defaults to 256): + Dimension of the layers exclude hybrid encoder. + num_queries (`int`, *optional*, defaults to 300): + Number of object queries. + decoder_in_channels (`list`, *optional*, defaults to `[256, 256, 256]`): + Multi level features dimension for decoder + decoder_ffn_dim (`int`, *optional*, defaults to 1024): + Dimension of the "intermediate" (often named feed-forward) layer in decoder. + num_feature_levels (`int`, *optional*, defaults to 3): + The number of input feature levels. + decoder_n_points (`int`, *optional*, defaults to 4): + The number of sampled keys in each feature level for each attention head in the decoder. + decoder_layers (`int`, *optional*, defaults to 6): + Number of decoder layers. + decoder_attention_heads (`int`, *optional*, defaults to 8): + Number of attention heads for each attention layer in the Transformer decoder. + decoder_activation_function (`str`, *optional*, defaults to `"relu"`): + The non-linear activation function (function or string) in the decoder. If string, `"gelu"`, + `"relu"`, `"silu"` and `"gelu_new"` are supported. + attention_dropout (`float`, *optional*, defaults to 0.0): + The dropout ratio for the attention probabilities. + num_denoising (`int`, *optional*, defaults to 100): + The total number of denoising tasks or queries to be used for contrastive denoising. + label_noise_ratio (`float`, *optional*, defaults to 0.5): + The fraction of denoising labels to which random noise should be added. + box_noise_scale (`float`, *optional*, defaults to 1.0): + Scale or magnitude of noise to be added to the bounding boxes. + learn_initial_query (`bool`, *optional*, defaults to `False`): + Indicates whether the initial query embeddings for the decoder should be learned during training + anchor_image_size (`tuple[int, int]`, *optional*): + Height and width of the input image used during evaluation to generate the bounding box anchors. If None, automatic generate anchor is applied. + with_box_refine (`bool`, *optional*, defaults to `True`): + Whether to apply iterative bounding box refinement, where each decoder layer refines the bounding boxes + based on the predictions from the previous layer. + is_encoder_decoder (`bool`, *optional*, defaults to `True`): + Whether the architecture has an encoder decoder structure. + matcher_alpha (`float`, *optional*, defaults to 0.25): + Parameter alpha used by the Hungarian Matcher. + matcher_gamma (`float`, *optional*, defaults to 2.0): + Parameter gamma used by the Hungarian Matcher. + matcher_class_cost (`float`, *optional*, defaults to 2.0): + The relative weight of the class loss used by the Hungarian Matcher. + matcher_bbox_cost (`float`, *optional*, defaults to 5.0): + The relative weight of the bounding box loss used by the Hungarian Matcher. + matcher_giou_cost (`float`, *optional*, defaults to 2.0): + The relative weight of the giou loss of used by the Hungarian Matcher. + use_focal_loss (`bool`, *optional*, defaults to `True`): + Parameter informing if focal loss should be used. + auxiliary_loss (`bool`, *optional*, defaults to `True`): + Whether auxiliary decoding losses (loss at each decoder layer) are to be used. + focal_loss_alpha (`float`, *optional*, defaults to 0.75): + Parameter alpha used to compute the focal loss. + focal_loss_gamma (`float`, *optional*, defaults to 2.0): + Parameter gamma used to compute the focal loss. + weight_loss_vfl (`float`, *optional*, defaults to 1.0): + Relative weight of the varifocal loss in the object detection loss. + weight_loss_bbox (`float`, *optional*, defaults to 5.0): + Relative weight of the L1 bounding box loss in the object detection loss. + weight_loss_giou (`float`, *optional*, defaults to 2.0): + Relative weight of the generalized IoU loss in the object detection loss. + eos_coefficient (`float`, *optional*, defaults to 0.0001): + Relative classification weight of the 'no-object' class in the object detection loss. + decoder_n_levels (`int`, *optional*, defaults to 3): + The number of feature levels used by the decoder. + decoder_offset_scale (`float`, *optional*, defaults to 0.5): + Scaling factor applied to the attention offsets in the decoder. + decoder_method (`str`, *optional*, defaults to `"default"`): + The method to use for the decoder: `"default"` or `"discrete"`. + tie_word_embeddings (`bool`, *optional*, defaults to `True`): + Whether to tie weight embeddings + + Examples: + + ```python + >>> from transformers import RTDetrV2Config, RTDetrV2Model + + >>> # Initializing a RT-DETR configuration + >>> configuration = RTDetrV2Config() + + >>> # Initializing a model (with random weights) from the configuration + >>> model = RTDetrV2Model(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ``` + """ + + model_type = "rt_detr_v2" + sub_configs = {"backbone_config": AutoConfig} + layer_types = ["basic", "bottleneck"] + attribute_map = { + "hidden_size": "d_model", + "num_attention_heads": "encoder_attention_heads", + } + + def __init__( + self, + initializer_range=0.01, + initializer_bias_prior_prob=None, + layer_norm_eps=1e-5, + batch_norm_eps=1e-5, + # backbone + backbone_config=None, + freeze_backbone_batch_norms=True, + # encoder HybridEncoder + encoder_hidden_dim=256, + encoder_in_channels=[512, 1024, 2048], + feat_strides=[8, 16, 32], + encoder_layers=1, + encoder_ffn_dim=1024, + encoder_attention_heads=8, + dropout=0.0, + activation_dropout=0.0, + encode_proj_layers=[2], + positional_encoding_temperature=10000, + encoder_activation_function="gelu", + activation_function="silu", + eval_size=None, + normalize_before=False, + hidden_expansion=1.0, + # decoder RTDetrV2Transformer + d_model=256, + num_queries=300, + decoder_in_channels=[256, 256, 256], + decoder_ffn_dim=1024, + num_feature_levels=3, + decoder_n_points=4, + decoder_layers=6, + decoder_attention_heads=8, + decoder_activation_function="relu", + attention_dropout=0.0, + num_denoising=100, + label_noise_ratio=0.5, + box_noise_scale=1.0, + learn_initial_query=False, + anchor_image_size=None, + with_box_refine=True, + is_encoder_decoder=True, + # Loss + matcher_alpha=0.25, + matcher_gamma=2.0, + matcher_class_cost=2.0, + matcher_bbox_cost=5.0, + matcher_giou_cost=2.0, + use_focal_loss=True, + auxiliary_loss=True, + focal_loss_alpha=0.75, + focal_loss_gamma=2.0, + weight_loss_vfl=1.0, + weight_loss_bbox=5.0, + weight_loss_giou=2.0, + eos_coefficient=1e-4, + decoder_n_levels=3, # default value + decoder_offset_scale=0.5, # default value + decoder_method="default", + tie_word_embeddings=True, + **kwargs, + ): + self.initializer_range = initializer_range + self.initializer_bias_prior_prob = initializer_bias_prior_prob + self.layer_norm_eps = layer_norm_eps + self.batch_norm_eps = batch_norm_eps + + backbone_config, kwargs = consolidate_backbone_kwargs_to_config( + backbone_config=backbone_config, + default_config_type="rt_detr_resnet", + default_config_kwargs={ + "out_indices": [2, 3, 4], + }, + **kwargs, + ) + + self.backbone_config = backbone_config + self.freeze_backbone_batch_norms = freeze_backbone_batch_norms + # encoder + self.encoder_hidden_dim = encoder_hidden_dim + self.encoder_in_channels = encoder_in_channels + self.feat_strides = feat_strides + self.encoder_ffn_dim = encoder_ffn_dim + self.dropout = dropout + self.activation_dropout = activation_dropout + self.encode_proj_layers = encode_proj_layers + self.encoder_layers = encoder_layers + self.positional_encoding_temperature = positional_encoding_temperature + self.eval_size = eval_size + self.normalize_before = normalize_before + self.encoder_activation_function = encoder_activation_function + self.activation_function = activation_function + self.hidden_expansion = hidden_expansion + self.num_queries = num_queries + self.decoder_ffn_dim = decoder_ffn_dim + self.decoder_in_channels = decoder_in_channels + self.num_feature_levels = num_feature_levels + self.decoder_n_points = decoder_n_points + self.decoder_layers = decoder_layers + self.decoder_attention_heads = decoder_attention_heads + self.decoder_activation_function = decoder_activation_function + self.attention_dropout = attention_dropout + self.num_denoising = num_denoising + self.label_noise_ratio = label_noise_ratio + self.box_noise_scale = box_noise_scale + self.learn_initial_query = learn_initial_query + self.anchor_image_size = anchor_image_size + self.auxiliary_loss = auxiliary_loss + self.with_box_refine = with_box_refine + # Loss + self.matcher_alpha = matcher_alpha + self.matcher_gamma = matcher_gamma + self.matcher_class_cost = matcher_class_cost + self.matcher_bbox_cost = matcher_bbox_cost + self.matcher_giou_cost = matcher_giou_cost + self.use_focal_loss = use_focal_loss + self.focal_loss_alpha = focal_loss_alpha + self.focal_loss_gamma = focal_loss_gamma + self.weight_loss_vfl = weight_loss_vfl + self.weight_loss_bbox = weight_loss_bbox + self.weight_loss_giou = weight_loss_giou + self.eos_coefficient = eos_coefficient + + if not hasattr(self, "d_model"): + self.d_model = d_model + + if not hasattr(self, "encoder_attention_heads"): + self.encoder_attention_heads = encoder_attention_heads + # add the new attributes with the given values or defaults + self.decoder_n_levels = decoder_n_levels + self.decoder_offset_scale = decoder_offset_scale + self.decoder_method = decoder_method + self.tie_word_embeddings = tie_word_embeddings + + super().__init__(is_encoder_decoder=is_encoder_decoder, **kwargs) + + +__all__ = ["RTDetrV2Config"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/rt_detr_v2/modeling_rt_detr_v2.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/rt_detr_v2/modeling_rt_detr_v2.py new file mode 100644 index 0000000000000000000000000000000000000000..b5244ffda7f83d97e40b71e5cfdb7ed7bfb78028 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/rt_detr_v2/modeling_rt_detr_v2.py @@ -0,0 +1,1873 @@ +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# This file was automatically generated from src/transformers/models/rt_detr_v2/modular_rt_detr_v2.py. +# Do NOT edit this file manually as any edits will be overwritten by the generation of +# the file from the modular. If any change should be done, please apply the change to the +# modular_rt_detr_v2.py file directly. One of our CI enforces this. +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# Copyright 2025 Baidu Inc and The HuggingFace Inc. team. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +import math +import warnings +from collections.abc import Callable +from dataclasses import dataclass + +import torch +import torch.nn as nn +import torch.nn.functional as F +from torch import Tensor + +from ... import initialization as init +from ...activations import ACT2CLS, ACT2FN +from ...backbone_utils import load_backbone +from ...image_transforms import center_to_corners_format, corners_to_center_format +from ...modeling_outputs import BaseModelOutput +from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel +from ...processing_utils import Unpack +from ...pytorch_utils import compile_compatible_method_lru_cache +from ...utils import ModelOutput, TransformersKwargs, auto_docstring, torch_compilable_check, torch_int +from ...utils.generic import can_return_tuple, merge_with_config_defaults +from ...utils.output_capturing import capture_outputs +from .configuration_rt_detr_v2 import RTDetrV2Config + + +def multi_scale_deformable_attention_v2( + value: Tensor, + value_spatial_shapes: Tensor, + sampling_locations: Tensor, + attention_weights: Tensor, + num_points_list: list[int], + method="default", +) -> Tensor: + batch_size, _, num_heads, hidden_dim = value.shape + _, num_queries, num_heads, num_levels, num_points = sampling_locations.shape + value_list = ( + value.permute(0, 2, 3, 1) + .flatten(0, 1) + .split([height * width for height, width in value_spatial_shapes], dim=-1) + ) + # sampling_offsets [8, 480, 8, 12, 2] + if method == "default": + sampling_grids = 2 * sampling_locations - 1 + elif method == "discrete": + sampling_grids = sampling_locations + sampling_grids = sampling_grids.permute(0, 2, 1, 3, 4).flatten(0, 1) + sampling_grids = sampling_grids.split(num_points_list, dim=-2) + sampling_value_list = [] + for level_id, (height, width) in enumerate(value_spatial_shapes): + # batch_size, height*width, num_heads, hidden_dim + # -> batch_size, height*width, num_heads*hidden_dim + # -> batch_size, num_heads*hidden_dim, height*width + # -> batch_size*num_heads, hidden_dim, height, width + value_l_ = value_list[level_id].reshape(batch_size * num_heads, hidden_dim, height, width) + # batch_size, num_queries, num_heads, num_points, 2 + # -> batch_size, num_heads, num_queries, num_points, 2 + # -> batch_size*num_heads, num_queries, num_points, 2 + sampling_grid_l_ = sampling_grids[level_id] + # batch_size*num_heads, hidden_dim, num_queries, num_points + if method == "default": + sampling_value_l_ = nn.functional.grid_sample( + value_l_, sampling_grid_l_, mode="bilinear", padding_mode="zeros", align_corners=False + ) + elif method == "discrete": + sampling_coord = (sampling_grid_l_ * torch.tensor([[width, height]], device=value.device) + 0.5).to( + torch.int64 + ) + + # Separate clamping for x and y coordinates + sampling_coord_x = sampling_coord[..., 0].clamp(0, width - 1) + sampling_coord_y = sampling_coord[..., 1].clamp(0, height - 1) + + # Combine the clamped coordinates + sampling_coord = torch.stack([sampling_coord_x, sampling_coord_y], dim=-1) + sampling_coord = sampling_coord.reshape(batch_size * num_heads, num_queries * num_points_list[level_id], 2) + sampling_idx = ( + torch.arange(sampling_coord.shape[0], device=value.device) + .unsqueeze(-1) + .repeat(1, sampling_coord.shape[1]) + ) + sampling_value_l_ = value_l_[sampling_idx, :, sampling_coord[..., 1], sampling_coord[..., 0]] + sampling_value_l_ = sampling_value_l_.permute(0, 2, 1).reshape( + batch_size * num_heads, hidden_dim, num_queries, num_points_list[level_id] + ) + sampling_value_list.append(sampling_value_l_) + # (batch_size, num_queries, num_heads, num_levels, num_points) + # -> (batch_size, num_heads, num_queries, num_levels, num_points) + # -> (batch_size, num_heads, 1, num_queries, num_levels*num_points) + attention_weights = attention_weights.permute(0, 2, 1, 3).reshape( + batch_size * num_heads, 1, num_queries, sum(num_points_list) + ) + output = ( + (torch.concat(sampling_value_list, dim=-1) * attention_weights) + .sum(-1) + .view(batch_size, num_heads * hidden_dim, num_queries) + ) + return output.transpose(1, 2).contiguous() + + +# the main change +class RTDetrV2MultiscaleDeformableAttention(nn.Module): + """ + RTDetrV2 version of multiscale deformable attention, extending the base implementation + with improved offset handling and initialization. + """ + + def __init__(self, config: RTDetrV2Config): + super().__init__() + num_heads = config.decoder_attention_heads + n_points = config.decoder_n_points + + if config.d_model % num_heads != 0: + raise ValueError( + f"embed_dim (d_model) must be divisible by num_heads, but got {config.d_model} and {num_heads}" + ) + dim_per_head = config.d_model // num_heads + # check if dim_per_head is power of 2 + if not ((dim_per_head & (dim_per_head - 1) == 0) and dim_per_head != 0): + warnings.warn( + "You'd better set embed_dim (d_model) in RTDetrV2MultiscaleDeformableAttention to make the" + " dimension of each attention head a power of 2 which is more efficient in the authors' CUDA" + " implementation." + ) + + self.im2col_step = 64 + + self.d_model = config.d_model + + # V2-specific attributes + self.n_levels = config.decoder_n_levels + self.n_heads = num_heads + self.n_points = n_points + + self.sampling_offsets = nn.Linear(config.d_model, num_heads * self.n_levels * n_points * 2) + self.attention_weights = nn.Linear(config.d_model, num_heads * self.n_levels * n_points) + self.value_proj = nn.Linear(config.d_model, config.d_model) + self.output_proj = nn.Linear(config.d_model, config.d_model) + + self.offset_scale = config.decoder_offset_scale + self.method = config.decoder_method + + # Initialize n_points list and scale + n_points_list = [self.n_points for _ in range(self.n_levels)] + self.n_points_list = n_points_list + n_points_scale = [1 / n for n in n_points_list for _ in range(n)] + self.register_buffer("n_points_scale", torch.tensor(n_points_scale, dtype=torch.float32)) + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.Tensor | None = None, + encoder_hidden_states=None, + encoder_attention_mask=None, + position_embeddings: torch.Tensor | None = None, + reference_points=None, + spatial_shapes=None, + spatial_shapes_list=None, + level_start_index=None, + **kwargs: Unpack[TransformersKwargs], + ): + # Process inputs up to sampling locations calculation using parent class logic + if position_embeddings is not None: + hidden_states = hidden_states + position_embeddings + + batch_size, num_queries, _ = hidden_states.shape + batch_size, sequence_length, _ = encoder_hidden_states.shape + torch_compilable_check( + (spatial_shapes[:, 0] * spatial_shapes[:, 1]).sum() == sequence_length, + "Make sure to align the spatial shapes with the sequence length of the encoder hidden states", + ) + + value = self.value_proj(encoder_hidden_states) + if attention_mask is not None: + value = value.masked_fill(~attention_mask[..., None], float(0)) + value = value.view(batch_size, sequence_length, self.n_heads, self.d_model // self.n_heads) + + # V2-specific sampling offsets shape + sampling_offsets = self.sampling_offsets(hidden_states).view( + batch_size, num_queries, self.n_heads, self.n_levels * self.n_points, 2 + ) + + attention_weights = self.attention_weights(hidden_states).view( + batch_size, num_queries, self.n_heads, self.n_levels * self.n_points + ) + attention_weights = F.softmax(attention_weights, -1) + + # V2-specific sampling locations calculation + if reference_points.shape[-1] == 2: + offset_normalizer = torch.stack([spatial_shapes[..., 1], spatial_shapes[..., 0]], -1) + sampling_locations = ( + reference_points[:, :, None, :, None, :] + + sampling_offsets / offset_normalizer[None, None, None, :, None, :] + ) + elif reference_points.shape[-1] == 4: + n_points_scale = self.n_points_scale.to(dtype=hidden_states.dtype).unsqueeze(-1) + offset = sampling_offsets * n_points_scale * reference_points[:, :, None, :, 2:] * self.offset_scale + sampling_locations = reference_points[:, :, None, :, :2] + offset + else: + raise ValueError(f"Last dim of reference_points must be 2 or 4, but got {reference_points.shape[-1]}") + + # V2-specific attention implementation choice + output = multi_scale_deformable_attention_v2( + value, spatial_shapes_list, sampling_locations, attention_weights, self.n_points_list, self.method + ) + + output = self.output_proj(output) + return output, attention_weights + + +class RTDetrV2MLP(nn.Module): + def __init__(self, config: RTDetrV2Config, hidden_size: int, intermediate_size: int, activation_function: str): + super().__init__() + self.fc1 = nn.Linear(hidden_size, intermediate_size) + self.fc2 = nn.Linear(intermediate_size, hidden_size) + self.activation_fn = ACT2FN[activation_function] + self.activation_dropout = config.activation_dropout + self.dropout = config.dropout + + def forward(self, hidden_states: torch.Tensor) -> torch.Tensor: + hidden_states = self.activation_fn(self.fc1(hidden_states)) + hidden_states = nn.functional.dropout(hidden_states, p=self.activation_dropout, training=self.training) + hidden_states = self.fc2(hidden_states) + hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training) + return hidden_states + + +def eager_attention_forward( + module: nn.Module, + query: torch.Tensor, + key: torch.Tensor, + value: torch.Tensor, + attention_mask: torch.Tensor | None, + scaling: float | None = None, + dropout: float = 0.0, + **kwargs: Unpack[TransformersKwargs], +): + if scaling is None: + scaling = query.size(-1) ** -0.5 + + # Take the dot product between "query" and "key" to get the raw attention scores. + attn_weights = torch.matmul(query, key.transpose(2, 3)) * scaling + + if attention_mask is not None: + attn_weights = attn_weights + attention_mask + + attn_weights = nn.functional.softmax(attn_weights, dim=-1) + attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training) + + attn_output = torch.matmul(attn_weights, value) + attn_output = attn_output.transpose(1, 2).contiguous() + + return attn_output, attn_weights + + +class RTDetrV2SelfAttention(nn.Module): + """ + Multi-headed self-attention from 'Attention Is All You Need' paper. + + In RT_DETR_V2, position embeddings are added to both queries and keys (but not values) in self-attention. + """ + + def __init__( + self, + config: RTDetrV2Config, + hidden_size: int, + num_attention_heads: int, + dropout: float = 0.0, + bias: bool = True, + ): + super().__init__() + self.config = config + self.head_dim = hidden_size // num_attention_heads + self.scaling = self.head_dim**-0.5 + self.attention_dropout = dropout + self.is_causal = False + + self.k_proj = nn.Linear(hidden_size, hidden_size, bias=bias) + self.v_proj = nn.Linear(hidden_size, hidden_size, bias=bias) + self.q_proj = nn.Linear(hidden_size, hidden_size, bias=bias) + self.o_proj = nn.Linear(hidden_size, hidden_size, bias=bias) + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.Tensor | None = None, + position_embeddings: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor, torch.Tensor]: + """ + Position embeddings are added to both queries and keys (but not values). + """ + input_shape = hidden_states.shape[:-1] + hidden_shape = (*input_shape, -1, self.head_dim) + + query_key_input = hidden_states + position_embeddings if position_embeddings is not None else hidden_states + + query_states = self.q_proj(query_key_input).view(hidden_shape).transpose(1, 2) + key_states = self.k_proj(query_key_input).view(hidden_shape).transpose(1, 2) + value_states = self.v_proj(hidden_states).view(hidden_shape).transpose(1, 2) + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, eager_attention_forward + ) + + attn_output, attn_weights = attention_interface( + self, + query_states, + key_states, + value_states, + attention_mask, + dropout=0.0 if not self.training else self.attention_dropout, + scaling=self.scaling, + **kwargs, + ) + + attn_output = attn_output.reshape(*input_shape, -1).contiguous() + attn_output = self.o_proj(attn_output) + return attn_output, attn_weights + + +class RTDetrV2DecoderLayer(nn.Module): + def __init__(self, config: RTDetrV2Config): + super().__init__() + self.hidden_size = config.d_model + + # self-attention + self.self_attn = RTDetrV2SelfAttention( + config=config, + hidden_size=self.hidden_size, + num_attention_heads=config.decoder_attention_heads, + dropout=config.attention_dropout, + ) + self.dropout = config.dropout + + self.self_attn_layer_norm = nn.LayerNorm(self.hidden_size, eps=config.layer_norm_eps) + # override only the encoder attention module with v2 version + self.encoder_attn = RTDetrV2MultiscaleDeformableAttention(config) + self.encoder_attn_layer_norm = nn.LayerNorm(self.hidden_size, eps=config.layer_norm_eps) + # feedforward neural networks + self.mlp = RTDetrV2MLP(config, self.hidden_size, config.decoder_ffn_dim, config.decoder_activation_function) + self.final_layer_norm = nn.LayerNorm(self.hidden_size, eps=config.layer_norm_eps) + + def forward( + self, + hidden_states: torch.Tensor, + object_queries_position_embeddings: torch.Tensor | None = None, + reference_points=None, + spatial_shapes=None, + spatial_shapes_list=None, + level_start_index=None, + encoder_hidden_states: torch.Tensor | None = None, + encoder_attention_mask: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> torch.Tensor: + """ + Args: + hidden_states (`torch.FloatTensor`): + Input to the layer of shape `(batch, seq_len, hidden_size)`. + object_queries_position_embeddings (`torch.FloatTensor`, *optional*): + Position embeddings for the object query slots. These are added to both queries and keys + in the self-attention layer (not values). + reference_points (`torch.FloatTensor`, *optional*): + Reference points. + spatial_shapes (`torch.LongTensor`, *optional*): + Spatial shapes. + level_start_index (`torch.LongTensor`, *optional*): + Level start index. + encoder_hidden_states (`torch.FloatTensor`): + cross attention input to the layer of shape `(batch, seq_len, hidden_size)` + encoder_attention_mask (`torch.FloatTensor`): encoder attention mask of size + `(batch, 1, target_len, source_len)` where padding elements are indicated by very large negative + values. + """ + residual = hidden_states + + # Self Attention + hidden_states, _ = self.self_attn( + hidden_states=hidden_states, + attention_mask=encoder_attention_mask, + position_embeddings=object_queries_position_embeddings, + **kwargs, + ) + + hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training) + hidden_states = residual + hidden_states + hidden_states = self.self_attn_layer_norm(hidden_states) + + residual = hidden_states + + # Cross-Attention + hidden_states, _ = self.encoder_attn( + hidden_states=hidden_states, + encoder_hidden_states=encoder_hidden_states, + position_embeddings=object_queries_position_embeddings, + reference_points=reference_points, + spatial_shapes=spatial_shapes, + spatial_shapes_list=spatial_shapes_list, + level_start_index=level_start_index, + **kwargs, + ) + + hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training) + hidden_states = residual + hidden_states + + hidden_states = self.encoder_attn_layer_norm(hidden_states) + + # Fully Connected + residual = hidden_states + hidden_states = self.mlp(hidden_states) + hidden_states = residual + hidden_states + hidden_states = self.final_layer_norm(hidden_states) + + return hidden_states + + +@auto_docstring +class RTDetrV2PreTrainedModel(PreTrainedModel): + config: RTDetrV2Config + base_model_prefix = "rt_detr_v2" + main_input_name = "pixel_values" + input_modalities = ("image",) + _no_split_modules = [r"RTDetrV2HybridEncoder", r"RTDetrV2DecoderLayer"] + _supports_sdpa = True + _supports_flash_attn = True + _supports_attention_backend = True + _supports_flex_attn = True + + @torch.no_grad() + def _init_weights(self, module): + """Initialize the weights""" + if isinstance(module, RTDetrV2ForObjectDetection): + if module.model.decoder.class_embed is not None: + for layer in module.model.decoder.class_embed: + prior_prob = self.config.initializer_bias_prior_prob or 1 / (self.config.num_labels + 1) + bias = float(-math.log((1 - prior_prob) / prior_prob)) + init.xavier_uniform_(layer.weight) + init.constant_(layer.bias, bias) + + if module.model.decoder.bbox_embed is not None: + for layer in module.model.decoder.bbox_embed: + init.constant_(layer.layers[-1].weight, 0) + init.constant_(layer.layers[-1].bias, 0) + + elif isinstance(module, RTDetrV2MultiscaleDeformableAttention): + init.constant_(module.sampling_offsets.weight, 0.0) + default_dtype = torch.get_default_dtype() + thetas = torch.arange(module.n_heads, dtype=torch.int64).to(default_dtype) * ( + 2.0 * math.pi / module.n_heads + ) + grid_init = torch.stack([thetas.cos(), thetas.sin()], -1) + grid_init = ( + (grid_init / grid_init.abs().max(-1, keepdim=True)[0]) + .view(module.n_heads, 1, 1, 2) + .repeat(1, module.n_levels, module.n_points, 1) + ) + for i in range(module.n_points): + grid_init[:, :, i, :] *= i + 1 + + init.copy_(module.sampling_offsets.bias, grid_init.view(-1)) + init.constant_(module.attention_weights.weight, 0.0) + init.constant_(module.attention_weights.bias, 0.0) + init.xavier_uniform_(module.value_proj.weight) + init.constant_(module.value_proj.bias, 0.0) + init.xavier_uniform_(module.output_proj.weight) + init.constant_(module.output_proj.bias, 0.0) + + elif isinstance(module, RTDetrV2Model): + prior_prob = self.config.initializer_bias_prior_prob or 1 / (self.config.num_labels + 1) + bias = float(-math.log((1 - prior_prob) / prior_prob)) + init.xavier_uniform_(module.enc_score_head.weight) + init.constant_(module.enc_score_head.bias, bias) + + elif isinstance(module, (nn.Linear, nn.Conv2d, nn.BatchNorm2d)): + init.normal_(module.weight, mean=0.0, std=self.config.initializer_range) + if module.bias is not None: + init.zeros_(module.bias) + if getattr(module, "running_mean", None) is not None: + init.zeros_(module.running_mean) + init.ones_(module.running_var) + init.zeros_(module.num_batches_tracked) + + elif isinstance(module, nn.LayerNorm): + init.ones_(module.weight) + init.zeros_(module.bias) + + if hasattr(module, "weight_embedding") and self.config.learn_initial_query: + init.xavier_uniform_(module.weight_embedding.weight) + if hasattr(module, "denoising_class_embed") and self.config.num_denoising > 0: + init.xavier_uniform_(module.denoising_class_embed.weight) + if isinstance(module, RTDetrV2MultiscaleDeformableAttention): + n_points_scale = [1 / n for n in module.n_points_list for _ in range(n)] + init.copy_(module.n_points_scale, torch.tensor(n_points_scale, dtype=torch.float32)) + + +@dataclass +@auto_docstring( + custom_intro=""" + Base class for outputs of the RTDetrV2Decoder. This class adds two attributes to + BaseModelOutputWithCrossAttentions, namely: + - a stacked tensor of intermediate decoder hidden states (i.e. the output of each decoder layer) + - a stacked tensor of intermediate reference points. + """ +) +class RTDetrV2DecoderOutput(ModelOutput): + r""" + intermediate_hidden_states (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, hidden_size)`): + Stacked intermediate hidden states (output of each layer of the decoder). + intermediate_logits (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, sequence_length, config.num_labels)`): + Stacked intermediate logits (logits of each layer of the decoder). + intermediate_reference_points (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, sequence_length, hidden_size)`): + Stacked intermediate reference points (reference points of each layer of the decoder). + intermediate_predicted_corners (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, 4)`): + Stacked intermediate predicted corners (predicted corners of each layer of the decoder). + initial_reference_points (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, 4)`): + Stacked initial reference points (initial reference points of each layer of the decoder). + cross_attentions (`tuple(torch.FloatTensor)`, *optional*, returned when `output_attentions=True` and `config.add_cross_attention=True` is passed or when `config.output_attentions=True`): + Tuple of `torch.FloatTensor` (one for each layer) of shape `(batch_size, num_heads, sequence_length, + sequence_length)`. Attentions weights of the decoder's cross-attention layer, after the attention softmax, + used to compute the weighted average in the cross-attention heads. + """ + + last_hidden_state: torch.FloatTensor | None = None + intermediate_hidden_states: torch.FloatTensor | None = None + intermediate_logits: torch.FloatTensor | None = None + intermediate_reference_points: torch.FloatTensor | None = None + intermediate_predicted_corners: torch.FloatTensor | None = None + initial_reference_points: torch.FloatTensor | None = None + hidden_states: tuple[torch.FloatTensor] | None = None + attentions: tuple[torch.FloatTensor] | None = None + cross_attentions: tuple[torch.FloatTensor] | None = None + + +def inverse_sigmoid(x, eps=1e-5): + x = x.clamp(min=0, max=1) + x1 = x.clamp(min=eps) + x2 = (1 - x).clamp(min=eps) + return torch.log(x1 / x2) + + +class RTDetrV2Decoder(RTDetrV2PreTrainedModel): + _can_record_outputs = { + "hidden_states": RTDetrV2DecoderLayer, + "attentions": RTDetrV2SelfAttention, + "cross_attentions": RTDetrV2MultiscaleDeformableAttention, + } + + def __init__(self, config: RTDetrV2Config): + super().__init__(config) + + self.dropout = config.dropout + self.layers = nn.ModuleList([RTDetrV2DecoderLayer(config) for _ in range(config.decoder_layers)]) + self.query_pos_head = RTDetrV2MLPPredictionHead(4, 2 * config.d_model, config.d_model, num_layers=2) + + # hack implementation for iterative bounding box refinement and two-stage Deformable DETR + self.bbox_embed = None + self.class_embed = None + + # Initialize weights and apply final processing + self.post_init() + + @merge_with_config_defaults + @capture_outputs + def forward( + self, + inputs_embeds=None, + encoder_hidden_states=None, + encoder_attention_mask=None, + reference_points=None, + spatial_shapes=None, + spatial_shapes_list=None, + level_start_index=None, + **kwargs: Unpack[TransformersKwargs], + ): + r""" + Args: + inputs_embeds (`torch.FloatTensor` of shape `(batch_size, num_queries, hidden_size)`): + The query embeddings that are passed into the decoder. + encoder_hidden_states (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*): + Sequence of hidden-states at the output of the last layer of the encoder. Used in the cross-attention + of the decoder. + encoder_attention_mask (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Mask to avoid performing cross-attention on padding pixel_values of the encoder. Mask values selected + in `[0, 1]`: + - 1 for pixels that are real (i.e. **not masked**), + - 0 for pixels that are padding (i.e. **masked**). + reference_points (`torch.FloatTensor` of shape `(batch_size, num_queries, 4)` is `as_two_stage` else `(batch_size, num_queries, 2)` or , *optional*): + Reference point in range `[0, 1]`, top-left (0,0), bottom-right (1, 1), including padding area. + spatial_shapes (`torch.FloatTensor` of shape `(num_feature_levels, 2)`): + Spatial shapes of the feature maps. + level_start_index (`torch.LongTensor` of shape `(num_feature_levels)`, *optional*): + Indexes for the start of each feature level. In range `[0, sequence_length]`. + """ + if inputs_embeds is not None: + hidden_states = inputs_embeds + + # decoder layers + intermediate = () + intermediate_reference_points = () + intermediate_logits = () + + reference_points = F.sigmoid(reference_points) + + # https://github.com/lyuwenyu/RT-DETR/blob/94f5e16708329d2f2716426868ec89aa774af016/RTDetrV2_pytorch/src/zoo/RTDetrV2/RTDetrV2_decoder.py#L252 + for idx, decoder_layer in enumerate(self.layers): + reference_points_input = reference_points.unsqueeze(2) + object_queries_position_embeddings = self.query_pos_head(reference_points) + + hidden_states = decoder_layer( + hidden_states, + object_queries_position_embeddings=object_queries_position_embeddings, + encoder_hidden_states=encoder_hidden_states, + reference_points=reference_points_input, + spatial_shapes=spatial_shapes, + spatial_shapes_list=spatial_shapes_list, + level_start_index=level_start_index, + encoder_attention_mask=encoder_attention_mask, + **kwargs, + ) + + # hack implementation for iterative bounding box refinement + if self.bbox_embed is not None: + predicted_corners = self.bbox_embed[idx](hidden_states) + new_reference_points = F.sigmoid(predicted_corners + inverse_sigmoid(reference_points)) + reference_points = new_reference_points.detach() + + intermediate += (hidden_states,) + intermediate_reference_points += ( + (new_reference_points,) if self.bbox_embed is not None else (reference_points,) + ) + + if self.class_embed is not None: + logits = self.class_embed[idx](hidden_states) + intermediate_logits += (logits,) + + # Keep batch_size as first dimension + intermediate = torch.stack(intermediate, dim=1) + intermediate_reference_points = torch.stack(intermediate_reference_points, dim=1) + if self.class_embed is not None: + intermediate_logits = torch.stack(intermediate_logits, dim=1) + + return RTDetrV2DecoderOutput( + last_hidden_state=hidden_states, + intermediate_hidden_states=intermediate, + intermediate_logits=intermediate_logits, + intermediate_reference_points=intermediate_reference_points, + ) + + +@dataclass +@auto_docstring( + custom_intro=""" + Base class for outputs of the RT-DETR encoder-decoder model. + """ +) +class RTDetrV2ModelOutput(ModelOutput): + r""" + last_hidden_state (`torch.FloatTensor` of shape `(batch_size, num_queries, hidden_size)`): + Sequence of hidden-states at the output of the last layer of the decoder of the model. + intermediate_hidden_states (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, hidden_size)`): + Stacked intermediate hidden states (output of each layer of the decoder). + intermediate_logits (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, sequence_length, config.num_labels)`): + Stacked intermediate logits (logits of each layer of the decoder). + intermediate_reference_points (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, 4)`): + Stacked intermediate reference points (reference points of each layer of the decoder). + intermediate_predicted_corners (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, 4)`): + Stacked intermediate predicted corners (predicted corners of each layer of the decoder). + initial_reference_points (`torch.FloatTensor` of shape `(batch_size, num_queries, 4)`): + Initial reference points used for the first decoder layer. + init_reference_points (`torch.FloatTensor` of shape `(batch_size, num_queries, 4)`): + Initial reference points sent through the Transformer decoder. + enc_topk_logits (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.num_labels)`): + Predicted bounding boxes scores where the top `config.two_stage_num_proposals` scoring bounding boxes are + picked as region proposals in the encoder stage. Output of bounding box binary classification (i.e. + foreground and background). + enc_topk_bboxes (`torch.FloatTensor` of shape `(batch_size, sequence_length, 4)`): + Logits of predicted bounding boxes coordinates in the encoder stage. + enc_outputs_class (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.num_labels)`, *optional*, returned when `config.with_box_refine=True` and `config.two_stage=True`): + Predicted bounding boxes scores where the top `config.two_stage_num_proposals` scoring bounding boxes are + picked as region proposals in the first stage. Output of bounding box binary classification (i.e. + foreground and background). + enc_outputs_coord_logits (`torch.FloatTensor` of shape `(batch_size, sequence_length, 4)`, *optional*, returned when `config.with_box_refine=True` and `config.two_stage=True`): + Logits of predicted bounding boxes coordinates in the first stage. + denoising_meta_values (`dict`): + Extra dictionary for the denoising related values. + """ + + last_hidden_state: torch.FloatTensor | None = None + intermediate_hidden_states: torch.FloatTensor | None = None + intermediate_logits: torch.FloatTensor | None = None + intermediate_reference_points: torch.FloatTensor | None = None + intermediate_predicted_corners: torch.FloatTensor | None = None + initial_reference_points: torch.FloatTensor | None = None + decoder_hidden_states: tuple[torch.FloatTensor] | None = None + decoder_attentions: tuple[torch.FloatTensor] | None = None + cross_attentions: tuple[torch.FloatTensor] | None = None + encoder_last_hidden_state: torch.FloatTensor | None = None + encoder_hidden_states: tuple[torch.FloatTensor] | None = None + encoder_attentions: tuple[torch.FloatTensor] | None = None + init_reference_points: torch.FloatTensor | None = None + enc_topk_logits: torch.FloatTensor | None = None + enc_topk_bboxes: torch.FloatTensor | None = None + enc_outputs_class: torch.FloatTensor | None = None + enc_outputs_coord_logits: torch.FloatTensor | None = None + denoising_meta_values: dict | None = None + + +class RTDetrV2FrozenBatchNorm2d(nn.Module): + """ + BatchNorm2d where the batch statistics and the affine parameters are fixed. + + Copy-paste from torchvision.misc.ops with added eps before rqsrt, without which any other models than + torchvision.models.resnet[18,34,50,101] produce nans. + """ + + def __init__(self, n): + super().__init__() + self.register_buffer("weight", torch.ones(n)) + self.register_buffer("bias", torch.zeros(n)) + self.register_buffer("running_mean", torch.zeros(n)) + self.register_buffer("running_var", torch.ones(n)) + + def _load_from_state_dict( + self, state_dict, prefix, local_metadata, strict, missing_keys, unexpected_keys, error_msgs + ): + num_batches_tracked_key = prefix + "num_batches_tracked" + if num_batches_tracked_key in state_dict: + del state_dict[num_batches_tracked_key] + + super()._load_from_state_dict( + state_dict, prefix, local_metadata, strict, missing_keys, unexpected_keys, error_msgs + ) + + def forward(self, x): + # move reshapes to the beginning + # to make it user-friendly + weight = self.weight.reshape(1, -1, 1, 1) + bias = self.bias.reshape(1, -1, 1, 1) + running_var = self.running_var.reshape(1, -1, 1, 1) + running_mean = self.running_mean.reshape(1, -1, 1, 1) + epsilon = 1e-5 + scale = weight * (running_var + epsilon).rsqrt() + bias = bias - running_mean * scale + return x * scale + bias + + +def replace_batch_norm(model): + r""" + Recursively replace all `torch.nn.BatchNorm2d` with `RTDetrV2FrozenBatchNorm2d`. + + Args: + model (torch.nn.Module): + input model + """ + for name, module in model.named_children(): + if isinstance(module, nn.BatchNorm2d): + new_module = RTDetrV2FrozenBatchNorm2d(module.num_features) + + if module.weight.device != torch.device("meta"): + new_module.weight.copy_(module.weight) + new_module.bias.copy_(module.bias) + new_module.running_mean.copy_(module.running_mean) + new_module.running_var.copy_(module.running_var) + + model._modules[name] = new_module + + if len(list(module.children())) > 0: + replace_batch_norm(module) + + +class RTDetrV2ConvEncoder(nn.Module): + """ + Convolutional backbone using the modeling_rt_detr_v2_resnet.py. + + nn.BatchNorm2d layers are replaced by RTDetrV2FrozenBatchNorm2d as defined above. + https://github.com/lyuwenyu/RT-DETR/blob/main/RTDetrV2_pytorch/src/nn/backbone/presnet.py#L142 + """ + + def __init__(self, config): + super().__init__() + + backbone = load_backbone(config) + + if config.freeze_backbone_batch_norms: + # replace batch norm by frozen batch norm + with torch.no_grad(): + replace_batch_norm(backbone) + self.model = backbone + self.intermediate_channel_sizes = self.model.channels + + def forward(self, pixel_values: torch.Tensor, pixel_mask: torch.Tensor): + # send pixel_values through the model to get list of feature maps + features = self.model(pixel_values).feature_maps + + out = [] + for feature_map in features: + # downsample pixel_mask to match shape of corresponding feature_map + mask = nn.functional.interpolate(pixel_mask[None].float(), size=feature_map.shape[-2:]).to(torch.bool)[0] + out.append((feature_map, mask)) + return out + + +class RTDetrV2ConvNormLayer(nn.Module): + def __init__(self, config, in_channels, out_channels, kernel_size, stride, padding=None, activation=None): + super().__init__() + self.conv = nn.Conv2d( + in_channels, + out_channels, + kernel_size, + stride, + padding=(kernel_size - 1) // 2 if padding is None else padding, + bias=False, + ) + self.norm = nn.BatchNorm2d(out_channels, config.batch_norm_eps) + self.activation = nn.Identity() if activation is None else ACT2CLS[activation]() + + def forward(self, hidden_state): + hidden_state = self.conv(hidden_state) + hidden_state = self.norm(hidden_state) + hidden_state = self.activation(hidden_state) + return hidden_state + + +class RTDetrV2EncoderLayer(nn.Module): + def __init__(self, config: RTDetrV2Config): + super().__init__() + self.normalize_before = config.normalize_before + self.hidden_size = config.encoder_hidden_dim + + # self-attention + self.self_attn = RTDetrV2SelfAttention( + config=config, + hidden_size=self.hidden_size, + num_attention_heads=config.num_attention_heads, + dropout=config.dropout, + ) + self.self_attn_layer_norm = nn.LayerNorm(self.hidden_size, eps=config.layer_norm_eps) + self.dropout = config.dropout + self.mlp = RTDetrV2MLP(config, self.hidden_size, config.encoder_ffn_dim, config.encoder_activation_function) + self.final_layer_norm = nn.LayerNorm(self.hidden_size, eps=config.layer_norm_eps) + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.Tensor, + spatial_position_embeddings: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> torch.Tensor: + """ + Args: + hidden_states (`torch.FloatTensor`): input to the layer of shape `(batch, seq_len, hidden_size)` + attention_mask (`torch.FloatTensor`): attention mask of size + `(batch, 1, target_len, source_len)` where padding elements are indicated by very large negative + values. + spatial_position_embeddings (`torch.FloatTensor`, *optional*): + Spatial position embeddings (2D positional encodings of image locations), to be added to both + the queries and keys in self-attention (but not to values). + """ + residual = hidden_states + if self.normalize_before: + hidden_states = self.self_attn_layer_norm(hidden_states) + + hidden_states, _ = self.self_attn( + hidden_states=hidden_states, + attention_mask=attention_mask, + position_embeddings=spatial_position_embeddings, + **kwargs, + ) + + hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training) + hidden_states = residual + hidden_states + if not self.normalize_before: + hidden_states = self.self_attn_layer_norm(hidden_states) + + if self.normalize_before: + hidden_states = self.final_layer_norm(hidden_states) + residual = hidden_states + + hidden_states = self.mlp(hidden_states) + + hidden_states = residual + hidden_states + if not self.normalize_before: + hidden_states = self.final_layer_norm(hidden_states) + + if self.training: + if not torch.isfinite(hidden_states).all(): + clamp_value = torch.finfo(hidden_states.dtype).max - 1000 + hidden_states = torch.clamp(hidden_states, min=-clamp_value, max=clamp_value) + + return hidden_states + + +class RTDetrV2RepVggBlock(nn.Module): + """ + RepVGG architecture block introduced by the work "RepVGG: Making VGG-style ConvNets Great Again". + """ + + def __init__(self, config: RTDetrV2Config): + super().__init__() + + activation = config.activation_function + hidden_channels = int(config.encoder_hidden_dim * config.hidden_expansion) + self.conv1 = RTDetrV2ConvNormLayer(config, hidden_channels, hidden_channels, 3, 1, padding=1) + self.conv2 = RTDetrV2ConvNormLayer(config, hidden_channels, hidden_channels, 1, 1, padding=0) + self.activation = nn.Identity() if activation is None else ACT2CLS[activation]() + + def forward(self, x): + y = self.conv1(x) + self.conv2(x) + return self.activation(y) + + +class RTDetrV2CSPRepLayer(nn.Module): + """ + Cross Stage Partial (CSP) network layer with RepVGG blocks. + """ + + def __init__(self, config: RTDetrV2Config): + super().__init__() + + in_channels = config.encoder_hidden_dim * 2 + out_channels = config.encoder_hidden_dim + num_blocks = 3 + activation = config.activation_function + + hidden_channels = int(out_channels * config.hidden_expansion) + self.conv1 = RTDetrV2ConvNormLayer(config, in_channels, hidden_channels, 1, 1, activation=activation) + self.conv2 = RTDetrV2ConvNormLayer(config, in_channels, hidden_channels, 1, 1, activation=activation) + self.bottlenecks = nn.Sequential(*[RTDetrV2RepVggBlock(config) for _ in range(num_blocks)]) + if hidden_channels != out_channels: + self.conv3 = RTDetrV2ConvNormLayer(config, hidden_channels, out_channels, 1, 1, activation=activation) + else: + self.conv3 = nn.Identity() + + def forward(self, hidden_state): + hidden_state_1 = self.conv1(hidden_state) + hidden_state_1 = self.bottlenecks(hidden_state_1) + hidden_state_2 = self.conv2(hidden_state) + return self.conv3(hidden_state_1 + hidden_state_2) + + +class RTDetrV2SinePositionEmbedding(nn.Module): + """ + 2D sinusoidal position embedding used in RT-DETR hybrid encoder. + """ + + def __init__(self, embed_dim: int = 256, temperature: int = 10000): + super().__init__() + self.embed_dim = embed_dim + self.temperature = temperature + + @compile_compatible_method_lru_cache(maxsize=32) + def forward( + self, + width: int, + height: int, + device: torch.device | str, + dtype: torch.dtype, + ) -> torch.Tensor: + """ + Generate 2D sinusoidal position embeddings. + + Returns: + Position embeddings of shape (1, height*width, embed_dim) + """ + grid_w = torch.arange(torch_int(width), device=device).to(dtype) + grid_h = torch.arange(torch_int(height), device=device).to(dtype) + grid_w, grid_h = torch.meshgrid(grid_w, grid_h, indexing="xy") + if self.embed_dim % 4 != 0: + raise ValueError("Embed dimension must be divisible by 4 for 2D sin-cos position embedding") + pos_dim = self.embed_dim // 4 + omega = torch.arange(pos_dim, device=device).to(dtype) / pos_dim + omega = 1.0 / (self.temperature**omega) + + out_w = grid_w.flatten()[..., None] @ omega[None] + out_h = grid_h.flatten()[..., None] @ omega[None] + + return torch.concat([out_h.sin(), out_h.cos(), out_w.sin(), out_w.cos()], dim=1)[None, :, :] + + +class RTDetrV2AIFILayer(nn.Module): + """ + AIFI (Attention-based Intra-scale Feature Interaction) layer used in RT-DETR hybrid encoder. + """ + + def __init__(self, config: RTDetrV2Config): + super().__init__() + self.config = config + self.encoder_hidden_dim = config.encoder_hidden_dim + self.eval_size = config.eval_size + + self.position_embedding = RTDetrV2SinePositionEmbedding( + embed_dim=self.encoder_hidden_dim, + temperature=config.positional_encoding_temperature, + ) + self.layers = nn.ModuleList([RTDetrV2EncoderLayer(config) for _ in range(config.encoder_layers)]) + + def forward( + self, + hidden_states: torch.Tensor, + **kwargs: Unpack[TransformersKwargs], + ) -> torch.Tensor: + """ + Args: + hidden_states (`torch.FloatTensor` of shape `(batch_size, channels, height, width)`): + Feature map to process. + """ + batch_size = hidden_states.shape[0] + height, width = hidden_states.shape[2:] + + hidden_states = hidden_states.flatten(2).permute(0, 2, 1) + + if self.training or self.eval_size is None: + pos_embed = self.position_embedding( + width=width, + height=height, + device=hidden_states.device, + dtype=hidden_states.dtype, + ) + else: + pos_embed = None + + for layer in self.layers: + hidden_states = layer( + hidden_states, + attention_mask=None, + spatial_position_embeddings=pos_embed, + **kwargs, + ) + + hidden_states = ( + hidden_states.permute(0, 2, 1).reshape(batch_size, self.encoder_hidden_dim, height, width).contiguous() + ) + + return hidden_states + + +class RTDetrV2HybridEncoder(RTDetrV2PreTrainedModel): + """ + Hybrid encoder consisting of AIFI (Attention-based Intra-scale Feature Interaction) layers, + a top-down Feature Pyramid Network (FPN) and a bottom-up Path Aggregation Network (PAN). + More details on the paper: https://huggingface.co/papers/2304.08069 + + Args: + config: RTDetrV2Config + """ + + _can_record_outputs = { + "hidden_states": RTDetrV2AIFILayer, + "attentions": RTDetrV2SelfAttention, + } + + def __init__(self, config: RTDetrV2Config): + super().__init__(config) + self.config = config + self.in_channels = config.encoder_in_channels + self.feat_strides = config.feat_strides + self.encoder_hidden_dim = config.encoder_hidden_dim + self.encode_proj_layers = config.encode_proj_layers + self.positional_encoding_temperature = config.positional_encoding_temperature + self.eval_size = config.eval_size + self.out_channels = [self.encoder_hidden_dim for _ in self.in_channels] + self.out_strides = self.feat_strides + self.num_fpn_stages = len(self.in_channels) - 1 + self.num_pan_stages = len(self.in_channels) - 1 + + # AIFI (Attention-based Intra-scale Feature Interaction) layers + self.aifi = nn.ModuleList([RTDetrV2AIFILayer(config) for _ in range(len(self.encode_proj_layers))]) + + # top-down FPN + self.lateral_convs = nn.ModuleList() + self.fpn_blocks = nn.ModuleList() + for _ in range(self.num_fpn_stages): + lateral_conv = RTDetrV2ConvNormLayer( + config, + in_channels=self.encoder_hidden_dim, + out_channels=self.encoder_hidden_dim, + kernel_size=1, + stride=1, + activation=config.activation_function, + ) + fpn_block = RTDetrV2CSPRepLayer(config) + self.lateral_convs.append(lateral_conv) + self.fpn_blocks.append(fpn_block) + + # bottom-up PAN + self.downsample_convs = nn.ModuleList() + self.pan_blocks = nn.ModuleList() + for _ in range(self.num_pan_stages): + downsample_conv = RTDetrV2ConvNormLayer( + config, + in_channels=self.encoder_hidden_dim, + out_channels=self.encoder_hidden_dim, + kernel_size=3, + stride=2, + activation=config.activation_function, + ) + pan_block = RTDetrV2CSPRepLayer(config) + self.downsample_convs.append(downsample_conv) + self.pan_blocks.append(pan_block) + + self.post_init() + + @merge_with_config_defaults + @capture_outputs(tie_last_hidden_states=False) + def forward( + self, + inputs_embeds=None, + **kwargs: Unpack[TransformersKwargs], + ) -> BaseModelOutput: + r""" + Args: + inputs_embeds (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`): + Flattened feature map (output of the backbone + projection layer) that is passed to the encoder. + """ + feature_maps = inputs_embeds + + # AIFI: Apply transformer encoder to specified feature levels + if self.config.encoder_layers > 0: + for i, enc_ind in enumerate(self.encode_proj_layers): + feature_maps[enc_ind] = self.aifi[i](feature_maps[enc_ind], **kwargs) + + # top-down FPN + fpn_feature_maps = [feature_maps[-1]] + for idx, (lateral_conv, fpn_block) in enumerate(zip(self.lateral_convs, self.fpn_blocks)): + backbone_feature_map = feature_maps[self.num_fpn_stages - idx - 1] + top_fpn_feature_map = fpn_feature_maps[-1] + # apply lateral block + top_fpn_feature_map = lateral_conv(top_fpn_feature_map) + fpn_feature_maps[-1] = top_fpn_feature_map + # apply fpn block + top_fpn_feature_map = F.interpolate(top_fpn_feature_map, scale_factor=2.0, mode="nearest") + fused_feature_map = torch.concat([top_fpn_feature_map, backbone_feature_map], dim=1) + new_fpn_feature_map = fpn_block(fused_feature_map) + fpn_feature_maps.append(new_fpn_feature_map) + + fpn_feature_maps.reverse() + + # bottom-up PAN + pan_feature_maps = [fpn_feature_maps[0]] + for idx, (downsample_conv, pan_block) in enumerate(zip(self.downsample_convs, self.pan_blocks)): + top_pan_feature_map = pan_feature_maps[-1] + fpn_feature_map = fpn_feature_maps[idx + 1] + downsampled_feature_map = downsample_conv(top_pan_feature_map) + fused_feature_map = torch.concat([downsampled_feature_map, fpn_feature_map], dim=1) + new_pan_feature_map = pan_block(fused_feature_map) + pan_feature_maps.append(new_pan_feature_map) + + return BaseModelOutput(last_hidden_state=pan_feature_maps) + + +def get_contrastive_denoising_training_group( + targets, + num_classes, + num_queries, + class_embed, + num_denoising_queries=100, + label_noise_ratio=0.5, + box_noise_scale=1.0, +): + """ + Creates a contrastive denoising training group using ground-truth samples. It adds noise to labels and boxes. + + Args: + targets (`list[dict]`): + The target objects, each containing 'class_labels' and 'boxes' for objects in an image. + num_classes (`int`): + Total number of classes in the dataset. + num_queries (`int`): + Number of query slots in the transformer. + class_embed (`callable`): + A function or a model layer to embed class labels. + num_denoising_queries (`int`, *optional*, defaults to 100): + Number of denoising queries. + label_noise_ratio (`float`, *optional*, defaults to 0.5): + Ratio of noise applied to labels. + box_noise_scale (`float`, *optional*, defaults to 1.0): + Scale of noise applied to bounding boxes. + Returns: + `tuple` comprising various elements: + - **input_query_class** (`torch.FloatTensor`) -- + Class queries with applied label noise. + - **input_query_bbox** (`torch.FloatTensor`) -- + Bounding box queries with applied box noise. + - **attn_mask** (`torch.FloatTensor`) -- + Attention mask for separating denoising and reconstruction queries. + - **denoising_meta_values** (`dict`) -- + Metadata including denoising positive indices, number of groups, and split sizes. + """ + + if num_denoising_queries <= 0: + return None, None, None, None + + num_ground_truths = [len(t["class_labels"]) for t in targets] + device = targets[0]["class_labels"].device + + max_gt_num = max(num_ground_truths) + if max_gt_num == 0: + return None, None, None, None + + num_groups_denoising_queries = num_denoising_queries // max_gt_num + num_groups_denoising_queries = 1 if num_groups_denoising_queries == 0 else num_groups_denoising_queries + # pad gt to max_num of a batch + batch_size = len(num_ground_truths) + + input_query_class = torch.full([batch_size, max_gt_num], num_classes, dtype=torch.int32, device=device) + input_query_bbox = torch.zeros([batch_size, max_gt_num, 4], device=device) + pad_gt_mask = torch.zeros([batch_size, max_gt_num], dtype=torch.bool, device=device) + + for i in range(batch_size): + num_gt = num_ground_truths[i] + if num_gt > 0: + input_query_class[i, :num_gt] = targets[i]["class_labels"] + input_query_bbox[i, :num_gt] = targets[i]["boxes"] + pad_gt_mask[i, :num_gt] = 1 + # each group has positive and negative queries. + input_query_class = input_query_class.tile([1, 2 * num_groups_denoising_queries]) + input_query_bbox = input_query_bbox.tile([1, 2 * num_groups_denoising_queries, 1]) + pad_gt_mask = pad_gt_mask.tile([1, 2 * num_groups_denoising_queries]) + # positive and negative mask + negative_gt_mask = torch.zeros([batch_size, max_gt_num * 2, 1], device=device) + negative_gt_mask[:, max_gt_num:] = 1 + negative_gt_mask = negative_gt_mask.tile([1, num_groups_denoising_queries, 1]) + positive_gt_mask = 1 - negative_gt_mask + # contrastive denoising training positive index + positive_gt_mask = positive_gt_mask.squeeze(-1) * pad_gt_mask + denoise_positive_idx = torch.nonzero(positive_gt_mask)[:, 1] + denoise_positive_idx = torch.split( + denoise_positive_idx, [n * num_groups_denoising_queries for n in num_ground_truths] + ) + # total denoising queries + num_denoising_queries = torch_int(max_gt_num * 2 * num_groups_denoising_queries) + + if label_noise_ratio > 0: + mask = torch.rand_like(input_query_class, dtype=torch.float) < (label_noise_ratio * 0.5) + # randomly put a new one here + new_label = torch.randint_like(mask, 0, num_classes, dtype=input_query_class.dtype) + input_query_class = torch.where(mask & pad_gt_mask, new_label, input_query_class) + + if box_noise_scale > 0: + known_bbox = center_to_corners_format(input_query_bbox) + diff = torch.tile(input_query_bbox[..., 2:] * 0.5, [1, 1, 2]) * box_noise_scale + rand_sign = torch.randint_like(input_query_bbox, 0, 2) * 2.0 - 1.0 + rand_part = torch.rand_like(input_query_bbox) + rand_part = (rand_part + 1.0) * negative_gt_mask + rand_part * (1 - negative_gt_mask) + rand_part *= rand_sign + known_bbox += rand_part * diff + known_bbox.clip_(min=0.0, max=1.0) + input_query_bbox = corners_to_center_format(known_bbox) + input_query_bbox = inverse_sigmoid(input_query_bbox) + + input_query_class = class_embed(input_query_class) + + target_size = num_denoising_queries + num_queries + attn_mask = torch.full([target_size, target_size], 0, dtype=torch.float, device=device) + # match query cannot see the reconstruction + attn_mask[num_denoising_queries:, :num_denoising_queries] = -torch.inf + + # reconstructions cannot see each other + for i in range(num_groups_denoising_queries): + idx_block_start = max_gt_num * 2 * i + idx_block_end = max_gt_num * 2 * (i + 1) + attn_mask[idx_block_start:idx_block_end, :idx_block_start] = -torch.inf + attn_mask[idx_block_start:idx_block_end, idx_block_end:num_denoising_queries] = -torch.inf + + denoising_meta_values = { + "dn_positive_idx": denoise_positive_idx, + "dn_num_group": num_groups_denoising_queries, + "dn_num_split": [num_denoising_queries, num_queries], + } + + return input_query_class, input_query_bbox, attn_mask, denoising_meta_values + + +@auto_docstring( + custom_intro=""" + RT-DETR Model (consisting of a backbone and encoder-decoder) outputting raw hidden states without any head on top. + """ +) +class RTDetrV2Model(RTDetrV2PreTrainedModel): + def __init__(self, config: RTDetrV2Config): + super().__init__(config) + + # Create backbone + self.backbone = RTDetrV2ConvEncoder(config) + intermediate_channel_sizes = self.backbone.intermediate_channel_sizes + + # Create encoder input projection layers + # https://github.com/lyuwenyu/RT-DETR/blob/94f5e16708329d2f2716426868ec89aa774af016/RTDetrV2_pytorch/src/zoo/RTDetrV2/hybrid_encoder.py#L212 + num_backbone_outs = len(intermediate_channel_sizes) + encoder_input_proj_list = [] + for i in range(num_backbone_outs): + in_channels = intermediate_channel_sizes[i] + encoder_input_proj_list.append( + nn.Sequential( + nn.Conv2d(in_channels, config.encoder_hidden_dim, kernel_size=1, bias=False), + nn.BatchNorm2d(config.encoder_hidden_dim), + ) + ) + self.encoder_input_proj = nn.ModuleList(encoder_input_proj_list) + + # Create encoder + self.encoder = RTDetrV2HybridEncoder(config) + + # denoising part + if config.num_denoising > 0: + self.denoising_class_embed = nn.Embedding( + config.num_labels + 1, config.d_model, padding_idx=config.num_labels + ) + + # decoder embedding + if config.learn_initial_query: + self.weight_embedding = nn.Embedding(config.num_queries, config.d_model) + + # encoder head + self.enc_output = nn.Sequential( + nn.Linear(config.d_model, config.d_model), + nn.LayerNorm(config.d_model, eps=config.layer_norm_eps), + ) + self.enc_score_head = nn.Linear(config.d_model, config.num_labels) + self.enc_bbox_head = RTDetrV2MLPPredictionHead(config.d_model, config.d_model, 4, num_layers=3) + + # init encoder output anchors and valid_mask + if config.anchor_image_size: + self.anchors, self.valid_mask = self.generate_anchors(dtype=self.dtype) + + # Create decoder input projection layers + # https://github.com/lyuwenyu/RT-DETR/blob/94f5e16708329d2f2716426868ec89aa774af016/RTDetrV2_pytorch/src/zoo/RTDetrV2/RTDetrV2_decoder.py#L412 + num_backbone_outs = len(config.decoder_in_channels) + decoder_input_proj_list = [] + for i in range(num_backbone_outs): + in_channels = config.decoder_in_channels[i] + decoder_input_proj_list.append( + nn.Sequential( + nn.Conv2d(in_channels, config.d_model, kernel_size=1, bias=False), + nn.BatchNorm2d(config.d_model, config.batch_norm_eps), + ) + ) + for _ in range(config.num_feature_levels - num_backbone_outs): + decoder_input_proj_list.append( + nn.Sequential( + nn.Conv2d(in_channels, config.d_model, kernel_size=3, stride=2, padding=1, bias=False), + nn.BatchNorm2d(config.d_model, config.batch_norm_eps), + ) + ) + in_channels = config.d_model + self.decoder_input_proj = nn.ModuleList(decoder_input_proj_list) + # decoder + self.decoder = RTDetrV2Decoder(config) + + self.post_init() + + def freeze_backbone(self): + for param in self.backbone.parameters(): + param.requires_grad_(False) + + def unfreeze_backbone(self): + for param in self.backbone.parameters(): + param.requires_grad_(True) + + @compile_compatible_method_lru_cache(maxsize=32) + def generate_anchors(self, spatial_shapes=None, grid_size=0.05, device="cpu", dtype=torch.float32): + if spatial_shapes is None: + spatial_shapes = [ + [int(self.config.anchor_image_size[0] / s), int(self.config.anchor_image_size[1] / s)] + for s in self.config.feat_strides + ] + anchors = [] + for level, (height, width) in enumerate(spatial_shapes): + grid_y, grid_x = torch.meshgrid( + torch.arange(end=height, device=device).to(dtype), + torch.arange(end=width, device=device).to(dtype), + indexing="ij", + ) + grid_xy = torch.stack([grid_x, grid_y], -1) + grid_xy = grid_xy.unsqueeze(0) + 0.5 + grid_xy[..., 0] /= width + grid_xy[..., 1] /= height + wh = torch.ones_like(grid_xy) * grid_size * (2.0**level) + anchors.append(torch.concat([grid_xy, wh], -1).reshape(-1, height * width, 4)) + # define the valid range for anchor coordinates + eps = 1e-2 + anchors = torch.concat(anchors, 1) + valid_mask = ((anchors > eps) * (anchors < 1 - eps)).all(-1, keepdim=True) + anchors = torch.log(anchors / (1 - anchors)) + anchors = torch.where(valid_mask, anchors, torch.tensor(torch.finfo(dtype).max, dtype=dtype, device=device)) + + return anchors, valid_mask + + @auto_docstring + @can_return_tuple + def forward( + self, + pixel_values: torch.FloatTensor, + pixel_mask: torch.LongTensor | None = None, + encoder_outputs: torch.FloatTensor | None = None, + inputs_embeds: torch.FloatTensor | None = None, + labels: list[dict] | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.FloatTensor] | RTDetrV2ModelOutput: + r""" + inputs_embeds (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*): + Optionally, instead of passing the flattened feature map (output of the backbone + projection layer), you + can choose to directly pass a flattened representation of an image. + labels (`list[Dict]` of len `(batch_size,)`, *optional*): + Labels for computing the bipartite matching loss. List of dicts, each dictionary containing at least the + following 2 keys: 'class_labels' and 'boxes' (the class labels and bounding boxes of an image in the batch + respectively). The class labels themselves should be a `torch.LongTensor` of len `(number of bounding boxes + in the image,)` and the boxes a `torch.FloatTensor` of shape `(number of bounding boxes in the image, 4)`. + + Examples: + + ```python + >>> from transformers import AutoImageProcessor, RTDetrV2Model + >>> from PIL import Image + >>> import requests + + >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg" + >>> image = Image.open(requests.get(url, stream=True).raw) + + >>> image_processor = AutoImageProcessor.from_pretrained("PekingU/RTDetrV2_r50vd") + >>> model = RTDetrV2Model.from_pretrained("PekingU/RTDetrV2_r50vd") + + >>> inputs = image_processor(images=image, return_tensors="pt") + + >>> outputs = model(**inputs) + + >>> last_hidden_states = outputs.last_hidden_state + >>> list(last_hidden_states.shape) + [1, 300, 256] + ```""" + if pixel_values is None and inputs_embeds is None: + raise ValueError("You have to specify either pixel_values or inputs_embeds") + + if inputs_embeds is None: + batch_size, num_channels, height, width = pixel_values.shape + device = pixel_values.device + if pixel_mask is None: + pixel_mask = torch.ones(((batch_size, height, width)), device=device) + features = self.backbone(pixel_values, pixel_mask) + proj_feats = [self.encoder_input_proj[level](source) for level, (source, mask) in enumerate(features)] + else: + batch_size = inputs_embeds.shape[0] + device = inputs_embeds.device + proj_feats = inputs_embeds + + if encoder_outputs is None: + encoder_outputs = self.encoder( + proj_feats, + **kwargs, + ) + # If the user passed a tuple for encoder_outputs, we wrap it in a BaseModelOutput + elif not isinstance(encoder_outputs, BaseModelOutput): + encoder_outputs = BaseModelOutput( + last_hidden_state=encoder_outputs[0], + hidden_states=encoder_outputs[1] if len(encoder_outputs) > 1 else None, + attentions=encoder_outputs[2] if len(encoder_outputs) > 2 else None, + ) + + # Equivalent to def _get_encoder_input + # https://github.com/lyuwenyu/RT-DETR/blob/94f5e16708329d2f2716426868ec89aa774af016/RTDetrV2_pytorch/src/zoo/RTDetrV2/RTDetrV2_decoder.py#L412 + sources = [] + for level, source in enumerate(encoder_outputs.last_hidden_state): + sources.append(self.decoder_input_proj[level](source)) + + # Lowest resolution feature maps are obtained via 3x3 stride 2 convolutions on the final stage + if self.config.num_feature_levels > len(sources): + _len_sources = len(sources) + sources.append(self.decoder_input_proj[_len_sources](encoder_outputs.last_hidden_state)[-1]) + for i in range(_len_sources + 1, self.config.num_feature_levels): + sources.append(self.decoder_input_proj[i](encoder_outputs.last_hidden_state[-1])) + + # Prepare encoder inputs (by flattening) + source_flatten = [] + spatial_shapes_list = [] + spatial_shapes = torch.empty((len(sources), 2), device=device, dtype=torch.long) + for level, source in enumerate(sources): + height, width = source.shape[-2:] + spatial_shapes[level, 0] = height + spatial_shapes[level, 1] = width + spatial_shapes_list.append((height, width)) + source = source.flatten(2).transpose(1, 2) + source_flatten.append(source) + source_flatten = torch.cat(source_flatten, 1) + level_start_index = torch.cat((spatial_shapes.new_zeros((1,)), spatial_shapes.prod(1).cumsum(0)[:-1])) + + # prepare denoising training + if self.training and self.config.num_denoising > 0 and labels is not None: + ( + denoising_class, + denoising_bbox_unact, + attention_mask, + denoising_meta_values, + ) = get_contrastive_denoising_training_group( + targets=labels, + num_classes=self.config.num_labels, + num_queries=self.config.num_queries, + class_embed=self.denoising_class_embed, + num_denoising_queries=self.config.num_denoising, + label_noise_ratio=self.config.label_noise_ratio, + box_noise_scale=self.config.box_noise_scale, + ) + else: + denoising_class, denoising_bbox_unact, attention_mask, denoising_meta_values = None, None, None, None + + batch_size = len(source_flatten) + device = source_flatten.device + dtype = source_flatten.dtype + + # prepare input for decoder + if self.training or self.config.anchor_image_size is None: + # Pass spatial_shapes as tuple to make it hashable and make sure + # lru_cache is working for generate_anchors() + spatial_shapes_tuple = tuple(spatial_shapes_list) + anchors, valid_mask = self.generate_anchors(spatial_shapes_tuple, device=device, dtype=dtype) + else: + anchors, valid_mask = self.anchors, self.valid_mask + anchors, valid_mask = anchors.to(device, dtype), valid_mask.to(device, dtype) + + # use the valid_mask to selectively retain values in the feature map where the mask is `True` + memory = valid_mask.to(source_flatten.dtype) * source_flatten + + output_memory = self.enc_output(memory) + + enc_outputs_class = self.enc_score_head(output_memory) + enc_outputs_coord_logits = self.enc_bbox_head(output_memory) + anchors + + _, topk_ind = torch.topk(enc_outputs_class.max(-1).values, self.config.num_queries, dim=1) + + reference_points_unact = enc_outputs_coord_logits.gather( + dim=1, index=topk_ind.unsqueeze(-1).repeat(1, 1, enc_outputs_coord_logits.shape[-1]) + ) + + enc_topk_bboxes = F.sigmoid(reference_points_unact) + if denoising_bbox_unact is not None: + reference_points_unact = torch.concat([denoising_bbox_unact, reference_points_unact], 1) + + enc_topk_logits = enc_outputs_class.gather( + dim=1, index=topk_ind.unsqueeze(-1).repeat(1, 1, enc_outputs_class.shape[-1]) + ) + + # extract region features + if self.config.learn_initial_query: + target = self.weight_embedding.tile([batch_size, 1, 1]) + else: + target = output_memory.gather(dim=1, index=topk_ind.unsqueeze(-1).repeat(1, 1, output_memory.shape[-1])) + target = target.detach() + + if denoising_class is not None: + target = torch.concat([denoising_class, target], 1) + + init_reference_points = reference_points_unact.detach() + + # decoder + decoder_outputs = self.decoder( + inputs_embeds=target, + encoder_hidden_states=source_flatten, + encoder_attention_mask=attention_mask, + reference_points=init_reference_points, + spatial_shapes=spatial_shapes, + spatial_shapes_list=spatial_shapes_list, + level_start_index=level_start_index, + **kwargs, + ) + + return RTDetrV2ModelOutput( + last_hidden_state=decoder_outputs.last_hidden_state, + intermediate_hidden_states=decoder_outputs.intermediate_hidden_states, + intermediate_logits=decoder_outputs.intermediate_logits, + intermediate_reference_points=decoder_outputs.intermediate_reference_points, + intermediate_predicted_corners=decoder_outputs.intermediate_predicted_corners, + initial_reference_points=decoder_outputs.initial_reference_points, + decoder_hidden_states=decoder_outputs.hidden_states, + decoder_attentions=decoder_outputs.attentions, + cross_attentions=decoder_outputs.cross_attentions, + encoder_last_hidden_state=encoder_outputs.last_hidden_state, + encoder_hidden_states=encoder_outputs.hidden_states, + encoder_attentions=encoder_outputs.attentions, + init_reference_points=init_reference_points, + enc_topk_logits=enc_topk_logits, + enc_topk_bboxes=enc_topk_bboxes, + enc_outputs_class=enc_outputs_class, + enc_outputs_coord_logits=enc_outputs_coord_logits, + denoising_meta_values=denoising_meta_values, + ) + + +class RTDetrV2MLPPredictionHead(nn.Module): + """ + Very simple multi-layer perceptron (MLP, also called FFN), used to predict the normalized center coordinates, + height and width of a bounding box w.r.t. an image. + + """ + + def __init__(self, input_dim, hidden_dim, output_dim, num_layers): + super().__init__() + self.num_layers = num_layers + h = [hidden_dim] * (num_layers - 1) + self.layers = nn.ModuleList(nn.Linear(n, k) for n, k in zip([input_dim] + h, h + [output_dim])) + + def forward(self, x): + for i, layer in enumerate(self.layers): + x = nn.functional.relu(layer(x)) if i < self.num_layers - 1 else layer(x) + return x + + +@dataclass +@auto_docstring( + custom_intro=""" + Output type of [`RTDetrV2ForObjectDetection`]. + """ +) +class RTDetrV2ObjectDetectionOutput(ModelOutput): + r""" + loss (`torch.FloatTensor` of shape `(1,)`, *optional*, returned when `labels` are provided)): + Total loss as a linear combination of a negative log-likehood (cross-entropy) for class prediction and a + bounding box loss. The latter is defined as a linear combination of the L1 loss and the generalized + scale-invariant IoU loss. + loss_dict (`Dict`, *optional*): + A dictionary containing the individual losses. Useful for logging. + logits (`torch.FloatTensor` of shape `(batch_size, num_queries, num_classes + 1)`): + Classification logits (including no-object) for all queries. + pred_boxes (`torch.FloatTensor` of shape `(batch_size, num_queries, 4)`): + Normalized boxes coordinates for all queries, represented as (center_x, center_y, width, height). These + values are normalized in [0, 1], relative to the size of each individual image in the batch (disregarding + possible padding). You can use [`~RTDetrV2ImageProcessor.post_process_object_detection`] to retrieve the + unnormalized (absolute) bounding boxes. + auxiliary_outputs (`list[Dict]`, *optional*): + Optional, only returned when auxiliary losses are activated (i.e. `config.auxiliary_loss` is set to `True`) + and labels are provided. It is a list of dictionaries containing the two above keys (`logits` and + `pred_boxes`) for each decoder layer. + last_hidden_state (`torch.FloatTensor` of shape `(batch_size, num_queries, hidden_size)`): + Sequence of hidden-states at the output of the last layer of the decoder of the model. + intermediate_hidden_states (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, hidden_size)`): + Stacked intermediate hidden states (output of each layer of the decoder). + intermediate_logits (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, config.num_labels)`): + Stacked intermediate logits (logits of each layer of the decoder). + intermediate_reference_points (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, 4)`): + Stacked intermediate reference points (reference points of each layer of the decoder). + intermediate_predicted_corners (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, 4)`): + Stacked intermediate predicted corners (predicted corners of each layer of the decoder). + initial_reference_points (`torch.FloatTensor` of shape `(batch_size, config.decoder_layers, num_queries, 4)`): + Stacked initial reference points (initial reference points of each layer of the decoder). + init_reference_points (`torch.FloatTensor` of shape `(batch_size, num_queries, 4)`): + Initial reference points sent through the Transformer decoder. + enc_topk_logits (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.num_labels)`, *optional*, returned when `config.with_box_refine=True` and `config.two_stage=True`): + Logits of predicted bounding boxes coordinates in the encoder. + enc_topk_bboxes (`torch.FloatTensor` of shape `(batch_size, sequence_length, 4)`, *optional*, returned when `config.with_box_refine=True` and `config.two_stage=True`): + Logits of predicted bounding boxes coordinates in the encoder. + enc_outputs_class (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.num_labels)`, *optional*, returned when `config.with_box_refine=True` and `config.two_stage=True`): + Predicted bounding boxes scores where the top `config.two_stage_num_proposals` scoring bounding boxes are + picked as region proposals in the first stage. Output of bounding box binary classification (i.e. + foreground and background). + enc_outputs_coord_logits (`torch.FloatTensor` of shape `(batch_size, sequence_length, 4)`, *optional*, returned when `config.with_box_refine=True` and `config.two_stage=True`): + Logits of predicted bounding boxes coordinates in the first stage. + denoising_meta_values (`dict`): + Extra dictionary for the denoising related values + """ + + loss: torch.FloatTensor | None = None + loss_dict: dict | None = None + logits: torch.FloatTensor | None = None + pred_boxes: torch.FloatTensor | None = None + auxiliary_outputs: list[dict] | None = None + last_hidden_state: torch.FloatTensor | None = None + intermediate_hidden_states: torch.FloatTensor | None = None + intermediate_logits: torch.FloatTensor | None = None + intermediate_reference_points: torch.FloatTensor | None = None + intermediate_predicted_corners: torch.FloatTensor | None = None + initial_reference_points: torch.FloatTensor | None = None + decoder_hidden_states: tuple[torch.FloatTensor] | None = None + decoder_attentions: tuple[torch.FloatTensor] | None = None + cross_attentions: tuple[torch.FloatTensor] | None = None + encoder_last_hidden_state: torch.FloatTensor | None = None + encoder_hidden_states: tuple[torch.FloatTensor] | None = None + encoder_attentions: tuple[torch.FloatTensor] | None = None + init_reference_points: tuple[torch.FloatTensor] | None = None + enc_topk_logits: torch.FloatTensor | None = None + enc_topk_bboxes: torch.FloatTensor | None = None + enc_outputs_class: torch.FloatTensor | None = None + enc_outputs_coord_logits: torch.FloatTensor | None = None + denoising_meta_values: dict | None = None + + +@auto_docstring( + custom_intro=""" + RT-DETR Model (consisting of a backbone and encoder-decoder) outputting bounding boxes and logits to be further + decoded into scores and classes. + """ +) +class RTDetrV2ForObjectDetection(RTDetrV2PreTrainedModel): + # When using clones, all layers > 0 will be clones, but layer 0 *is* required + # We can't initialize the model on meta device as some weights are modified during the initialization + _no_split_modules = None + _tied_weights_keys = { + r"bbox_embed.(?![0])\d+": r"bbox_embed.0", + r"class_embed.(?![0])\d+": r"^class_embed.0", + "class_embed": "model.decoder.class_embed", + "bbox_embed": "model.decoder.bbox_embed", + } + + def __init__(self, config: RTDetrV2Config): + super().__init__(config) + # RTDETR encoder-decoder model + self.model = RTDetrV2Model(config) + self.class_embed = nn.ModuleList( + [torch.nn.Linear(config.d_model, config.num_labels) for _ in range(config.decoder_layers)] + ) + self.bbox_embed = nn.ModuleList( + [ + RTDetrV2MLPPredictionHead(config.d_model, config.d_model, 4, num_layers=3) + for _ in range(config.decoder_layers) + ] + ) + self.model.decoder.class_embed = self.class_embed + self.model.decoder.bbox_embed = self.bbox_embed + + # Initialize weights and apply final processing + self.post_init() + + def _set_aux_loss(self, outputs_class, outputs_coord): + return [{"logits": a, "pred_boxes": b} for a, b in zip(outputs_class, outputs_coord)] + + @auto_docstring + @can_return_tuple + def forward( + self, + pixel_values: torch.FloatTensor, + pixel_mask: torch.LongTensor | None = None, + encoder_outputs: torch.FloatTensor | None = None, + inputs_embeds: torch.FloatTensor | None = None, + labels: list[dict] | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.FloatTensor] | RTDetrV2ObjectDetectionOutput: + r""" + inputs_embeds (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*): + Optionally, instead of passing the flattened feature map (output of the backbone + projection layer), you + can choose to directly pass a flattened representation of an image. + labels (`list[Dict]` of len `(batch_size,)`, *optional*): + Labels for computing the bipartite matching loss. List of dicts, each dictionary containing at least the + following 2 keys: 'class_labels' and 'boxes' (the class labels and bounding boxes of an image in the batch + respectively). The class labels themselves should be a `torch.LongTensor` of len `(number of bounding boxes + in the image,)` and the boxes a `torch.FloatTensor` of shape `(number of bounding boxes in the image, 4)`. + + Examples: + + ```python + >>> from transformers import RTDetrV2ImageProcessor, RTDetrV2ForObjectDetection + >>> from PIL import Image + >>> import requests + >>> import torch + + >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg" + >>> image = Image.open(requests.get(url, stream=True).raw) + + >>> image_processor = RTDetrV2ImageProcessor.from_pretrained("PekingU/RTDetrV2_r50vd") + >>> model = RTDetrV2ForObjectDetection.from_pretrained("PekingU/RTDetrV2_r50vd") + + >>> # prepare image for the model + >>> inputs = image_processor(images=image, return_tensors="pt") + + >>> # forward pass + >>> outputs = model(**inputs) + + >>> logits = outputs.logits + >>> list(logits.shape) + [1, 300, 80] + + >>> boxes = outputs.pred_boxes + >>> list(boxes.shape) + [1, 300, 4] + + >>> # convert outputs (bounding boxes and class logits) to Pascal VOC format (xmin, ymin, xmax, ymax) + >>> target_sizes = torch.tensor([image.size[::-1]]) + >>> results = image_processor.post_process_object_detection(outputs, threshold=0.9, target_sizes=target_sizes)[ + ... 0 + ... ] + + >>> for score, label, box in zip(results["scores"], results["labels"], results["boxes"]): + ... box = [round(i, 2) for i in box.tolist()] + ... print( + ... f"Detected {model.config.id2label[label.item()]} with confidence " + ... f"{round(score.item(), 3)} at location {box}" + ... ) + Detected sofa with confidence 0.97 at location [0.14, 0.38, 640.13, 476.21] + Detected cat with confidence 0.96 at location [343.38, 24.28, 640.14, 371.5] + Detected cat with confidence 0.958 at location [13.23, 54.18, 318.98, 472.22] + Detected remote with confidence 0.951 at location [40.11, 73.44, 175.96, 118.48] + Detected remote with confidence 0.924 at location [333.73, 76.58, 369.97, 186.99] + ```""" + outputs = self.model( + pixel_values, + pixel_mask=pixel_mask, + encoder_outputs=encoder_outputs, + inputs_embeds=inputs_embeds, + labels=labels, + **kwargs, + ) + + denoising_meta_values = outputs.denoising_meta_values if self.training else None + + outputs_class = outputs.intermediate_logits + outputs_coord = outputs.intermediate_reference_points + predicted_corners = outputs.intermediate_predicted_corners + initial_reference_points = outputs.initial_reference_points + + logits = outputs_class[:, -1] + pred_boxes = outputs_coord[:, -1] + + loss, loss_dict, auxiliary_outputs, enc_topk_logits, enc_topk_bboxes = None, None, None, None, None + if labels is not None: + enc_topk_logits = outputs.enc_topk_logits + enc_topk_bboxes = outputs.enc_topk_bboxes + loss, loss_dict, auxiliary_outputs = self.loss_function( + logits, + labels, + self.device, + pred_boxes, + self.config, + outputs_class, + outputs_coord, + enc_topk_logits=enc_topk_logits, + enc_topk_bboxes=enc_topk_bboxes, + denoising_meta_values=denoising_meta_values, + predicted_corners=predicted_corners, + initial_reference_points=initial_reference_points, + **kwargs, + ) + + return RTDetrV2ObjectDetectionOutput( + loss=loss, + loss_dict=loss_dict, + logits=logits, + pred_boxes=pred_boxes, + auxiliary_outputs=auxiliary_outputs, + last_hidden_state=outputs.last_hidden_state, + intermediate_hidden_states=outputs.intermediate_hidden_states, + intermediate_logits=outputs.intermediate_logits, + intermediate_reference_points=outputs.intermediate_reference_points, + intermediate_predicted_corners=outputs.intermediate_predicted_corners, + initial_reference_points=outputs.initial_reference_points, + decoder_hidden_states=outputs.decoder_hidden_states, + decoder_attentions=outputs.decoder_attentions, + cross_attentions=outputs.cross_attentions, + encoder_last_hidden_state=outputs.encoder_last_hidden_state, + encoder_hidden_states=outputs.encoder_hidden_states, + encoder_attentions=outputs.encoder_attentions, + init_reference_points=outputs.init_reference_points, + enc_topk_logits=outputs.enc_topk_logits, + enc_topk_bboxes=outputs.enc_topk_bboxes, + enc_outputs_class=outputs.enc_outputs_class, + enc_outputs_coord_logits=outputs.enc_outputs_coord_logits, + denoising_meta_values=outputs.denoising_meta_values, + ) + + +__all__ = ["RTDetrV2Model", "RTDetrV2PreTrainedModel", "RTDetrV2ForObjectDetection"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/rt_detr_v2/modular_rt_detr_v2.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/rt_detr_v2/modular_rt_detr_v2.py new file mode 100644 index 0000000000000000000000000000000000000000..1272d97d029f4b5072d267707630412a9d093394 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/rt_detr_v2/modular_rt_detr_v2.py @@ -0,0 +1,582 @@ +# Copyright 2025 Baidu Inc and The HuggingFace Inc. team. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +import warnings + +import torch +import torch.nn as nn +import torch.nn.functional as F +from torch import Tensor + +from ... import initialization as init +from ...backbone_utils import consolidate_backbone_kwargs_to_config +from ...configuration_utils import PreTrainedConfig +from ...processing_utils import Unpack +from ...utils import TransformersKwargs, logging, torch_compilable_check +from ..auto import AutoConfig +from ..rt_detr.modeling_rt_detr import ( + RTDetrDecoder, + RTDetrDecoderLayer, + RTDetrForObjectDetection, + RTDetrMLPPredictionHead, + RTDetrModel, + RTDetrPreTrainedModel, +) + + +logger = logging.get_logger(__name__) + + +class RTDetrV2Config(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`RTDetrV2Model`]. It is used to instantiate a + RT-DETR model according to the specified arguments, defining the model architecture. Instantiating a configuration + with the defaults will yield a similar configuration to that of the RT-DETR architecture. + + e.g. [PekingU/rtdetr_r18vd](https://huggingface.co/PekingU/rtdetr_r18vd) + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + initializer_range (`float`, *optional*, defaults to 0.01): + The standard deviation of the truncated_normal_initializer for initializing all weight matrices. + initializer_bias_prior_prob (`float`, *optional*): + The prior probability used by the bias initializer to initialize biases for `enc_score_head` and `class_embed`. + If `None`, `prior_prob` computed as `prior_prob = 1 / (num_labels + 1)` while initializing model weights. + layer_norm_eps (`float`, *optional*, defaults to 1e-05): + The epsilon used by the layer normalization layers. + batch_norm_eps (`float`, *optional*, defaults to 1e-05): + The epsilon used by the batch normalization layers. + backbone_config (`Union[dict, "PreTrainedConfig"]`, *optional*, defaults to `RTDetrV2ResNetConfig()`): + The configuration of the backbone model. + freeze_backbone_batch_norms (`bool`, *optional*, defaults to `True`): + Whether to freeze the batch normalization layers in the backbone. + encoder_hidden_dim (`int`, *optional*, defaults to 256): + Dimension of the layers in hybrid encoder. + encoder_in_channels (`list`, *optional*, defaults to `[512, 1024, 2048]`): + Multi level features input for encoder. + feat_strides (`list[int]`, *optional*, defaults to `[8, 16, 32]`): + Strides used in each feature map. + encoder_layers (`int`, *optional*, defaults to 1): + Total of layers to be used by the encoder. + encoder_ffn_dim (`int`, *optional*, defaults to 1024): + Dimension of the "intermediate" (often named feed-forward) layer in decoder. + encoder_attention_heads (`int`, *optional*, defaults to 8): + Number of attention heads for each attention layer in the Transformer encoder. + dropout (`float`, *optional*, defaults to 0.0): + The ratio for all dropout layers. + activation_dropout (`float`, *optional*, defaults to 0.0): + The dropout ratio for activations inside the fully connected layer. + encode_proj_layers (`list[int]`, *optional*, defaults to `[2]`): + Indexes of the projected layers to be used in the encoder. + positional_encoding_temperature (`int`, *optional*, defaults to 10000): + The temperature parameter used to create the positional encodings. + encoder_activation_function (`str`, *optional*, defaults to `"gelu"`): + The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`, + `"relu"`, `"silu"` and `"gelu_new"` are supported. + activation_function (`str`, *optional*, defaults to `"silu"`): + The non-linear activation function (function or string) in the general layer. If string, `"gelu"`, + `"relu"`, `"silu"` and `"gelu_new"` are supported. + eval_size (`tuple[int, int]`, *optional*): + Height and width used to compute the effective height and width of the position embeddings after taking + into account the stride. + normalize_before (`bool`, *optional*, defaults to `False`): + Determine whether to apply layer normalization in the transformer encoder layer before self-attention and + feed-forward modules. + hidden_expansion (`float`, *optional*, defaults to 1.0): + Expansion ratio to enlarge the dimension size of RepVGGBlock and CSPRepLayer. + d_model (`int`, *optional*, defaults to 256): + Dimension of the layers exclude hybrid encoder. + num_queries (`int`, *optional*, defaults to 300): + Number of object queries. + decoder_in_channels (`list`, *optional*, defaults to `[256, 256, 256]`): + Multi level features dimension for decoder + decoder_ffn_dim (`int`, *optional*, defaults to 1024): + Dimension of the "intermediate" (often named feed-forward) layer in decoder. + num_feature_levels (`int`, *optional*, defaults to 3): + The number of input feature levels. + decoder_n_points (`int`, *optional*, defaults to 4): + The number of sampled keys in each feature level for each attention head in the decoder. + decoder_layers (`int`, *optional*, defaults to 6): + Number of decoder layers. + decoder_attention_heads (`int`, *optional*, defaults to 8): + Number of attention heads for each attention layer in the Transformer decoder. + decoder_activation_function (`str`, *optional*, defaults to `"relu"`): + The non-linear activation function (function or string) in the decoder. If string, `"gelu"`, + `"relu"`, `"silu"` and `"gelu_new"` are supported. + attention_dropout (`float`, *optional*, defaults to 0.0): + The dropout ratio for the attention probabilities. + num_denoising (`int`, *optional*, defaults to 100): + The total number of denoising tasks or queries to be used for contrastive denoising. + label_noise_ratio (`float`, *optional*, defaults to 0.5): + The fraction of denoising labels to which random noise should be added. + box_noise_scale (`float`, *optional*, defaults to 1.0): + Scale or magnitude of noise to be added to the bounding boxes. + learn_initial_query (`bool`, *optional*, defaults to `False`): + Indicates whether the initial query embeddings for the decoder should be learned during training + anchor_image_size (`tuple[int, int]`, *optional*): + Height and width of the input image used during evaluation to generate the bounding box anchors. If None, automatic generate anchor is applied. + with_box_refine (`bool`, *optional*, defaults to `True`): + Whether to apply iterative bounding box refinement, where each decoder layer refines the bounding boxes + based on the predictions from the previous layer. + is_encoder_decoder (`bool`, *optional*, defaults to `True`): + Whether the architecture has an encoder decoder structure. + matcher_alpha (`float`, *optional*, defaults to 0.25): + Parameter alpha used by the Hungarian Matcher. + matcher_gamma (`float`, *optional*, defaults to 2.0): + Parameter gamma used by the Hungarian Matcher. + matcher_class_cost (`float`, *optional*, defaults to 2.0): + The relative weight of the class loss used by the Hungarian Matcher. + matcher_bbox_cost (`float`, *optional*, defaults to 5.0): + The relative weight of the bounding box loss used by the Hungarian Matcher. + matcher_giou_cost (`float`, *optional*, defaults to 2.0): + The relative weight of the giou loss of used by the Hungarian Matcher. + use_focal_loss (`bool`, *optional*, defaults to `True`): + Parameter informing if focal loss should be used. + auxiliary_loss (`bool`, *optional*, defaults to `True`): + Whether auxiliary decoding losses (loss at each decoder layer) are to be used. + focal_loss_alpha (`float`, *optional*, defaults to 0.75): + Parameter alpha used to compute the focal loss. + focal_loss_gamma (`float`, *optional*, defaults to 2.0): + Parameter gamma used to compute the focal loss. + weight_loss_vfl (`float`, *optional*, defaults to 1.0): + Relative weight of the varifocal loss in the object detection loss. + weight_loss_bbox (`float`, *optional*, defaults to 5.0): + Relative weight of the L1 bounding box loss in the object detection loss. + weight_loss_giou (`float`, *optional*, defaults to 2.0): + Relative weight of the generalized IoU loss in the object detection loss. + eos_coefficient (`float`, *optional*, defaults to 0.0001): + Relative classification weight of the 'no-object' class in the object detection loss. + decoder_n_levels (`int`, *optional*, defaults to 3): + The number of feature levels used by the decoder. + decoder_offset_scale (`float`, *optional*, defaults to 0.5): + Scaling factor applied to the attention offsets in the decoder. + decoder_method (`str`, *optional*, defaults to `"default"`): + The method to use for the decoder: `"default"` or `"discrete"`. + tie_word_embeddings (`bool`, *optional*, defaults to `True`): + Whether to tie weight embeddings + + Examples: + + ```python + >>> from transformers import RTDetrV2Config, RTDetrV2Model + + >>> # Initializing a RT-DETR configuration + >>> configuration = RTDetrV2Config() + + >>> # Initializing a model (with random weights) from the configuration + >>> model = RTDetrV2Model(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ``` + """ + + model_type = "rt_detr_v2" + sub_configs = {"backbone_config": AutoConfig} + layer_types = ["basic", "bottleneck"] + attribute_map = { + "hidden_size": "d_model", + "num_attention_heads": "encoder_attention_heads", + } + + def __init__( + self, + initializer_range=0.01, + initializer_bias_prior_prob=None, + layer_norm_eps=1e-5, + batch_norm_eps=1e-5, + # backbone + backbone_config=None, + freeze_backbone_batch_norms=True, + # encoder HybridEncoder + encoder_hidden_dim=256, + encoder_in_channels=[512, 1024, 2048], + feat_strides=[8, 16, 32], + encoder_layers=1, + encoder_ffn_dim=1024, + encoder_attention_heads=8, + dropout=0.0, + activation_dropout=0.0, + encode_proj_layers=[2], + positional_encoding_temperature=10000, + encoder_activation_function="gelu", + activation_function="silu", + eval_size=None, + normalize_before=False, + hidden_expansion=1.0, + # decoder RTDetrV2Transformer + d_model=256, + num_queries=300, + decoder_in_channels=[256, 256, 256], + decoder_ffn_dim=1024, + num_feature_levels=3, + decoder_n_points=4, + decoder_layers=6, + decoder_attention_heads=8, + decoder_activation_function="relu", + attention_dropout=0.0, + num_denoising=100, + label_noise_ratio=0.5, + box_noise_scale=1.0, + learn_initial_query=False, + anchor_image_size=None, + with_box_refine=True, + is_encoder_decoder=True, + # Loss + matcher_alpha=0.25, + matcher_gamma=2.0, + matcher_class_cost=2.0, + matcher_bbox_cost=5.0, + matcher_giou_cost=2.0, + use_focal_loss=True, + auxiliary_loss=True, + focal_loss_alpha=0.75, + focal_loss_gamma=2.0, + weight_loss_vfl=1.0, + weight_loss_bbox=5.0, + weight_loss_giou=2.0, + eos_coefficient=1e-4, + decoder_n_levels=3, # default value + decoder_offset_scale=0.5, # default value + decoder_method="default", + tie_word_embeddings=True, + **kwargs, + ): + self.initializer_range = initializer_range + self.initializer_bias_prior_prob = initializer_bias_prior_prob + self.layer_norm_eps = layer_norm_eps + self.batch_norm_eps = batch_norm_eps + + backbone_config, kwargs = consolidate_backbone_kwargs_to_config( + backbone_config=backbone_config, + default_config_type="rt_detr_resnet", + default_config_kwargs={ + "out_indices": [2, 3, 4], + }, + **kwargs, + ) + + self.backbone_config = backbone_config + self.freeze_backbone_batch_norms = freeze_backbone_batch_norms + # encoder + self.encoder_hidden_dim = encoder_hidden_dim + self.encoder_in_channels = encoder_in_channels + self.feat_strides = feat_strides + self.encoder_ffn_dim = encoder_ffn_dim + self.dropout = dropout + self.activation_dropout = activation_dropout + self.encode_proj_layers = encode_proj_layers + self.encoder_layers = encoder_layers + self.positional_encoding_temperature = positional_encoding_temperature + self.eval_size = eval_size + self.normalize_before = normalize_before + self.encoder_activation_function = encoder_activation_function + self.activation_function = activation_function + self.hidden_expansion = hidden_expansion + self.num_queries = num_queries + self.decoder_ffn_dim = decoder_ffn_dim + self.decoder_in_channels = decoder_in_channels + self.num_feature_levels = num_feature_levels + self.decoder_n_points = decoder_n_points + self.decoder_layers = decoder_layers + self.decoder_attention_heads = decoder_attention_heads + self.decoder_activation_function = decoder_activation_function + self.attention_dropout = attention_dropout + self.num_denoising = num_denoising + self.label_noise_ratio = label_noise_ratio + self.box_noise_scale = box_noise_scale + self.learn_initial_query = learn_initial_query + self.anchor_image_size = anchor_image_size + self.auxiliary_loss = auxiliary_loss + self.with_box_refine = with_box_refine + # Loss + self.matcher_alpha = matcher_alpha + self.matcher_gamma = matcher_gamma + self.matcher_class_cost = matcher_class_cost + self.matcher_bbox_cost = matcher_bbox_cost + self.matcher_giou_cost = matcher_giou_cost + self.use_focal_loss = use_focal_loss + self.focal_loss_alpha = focal_loss_alpha + self.focal_loss_gamma = focal_loss_gamma + self.weight_loss_vfl = weight_loss_vfl + self.weight_loss_bbox = weight_loss_bbox + self.weight_loss_giou = weight_loss_giou + self.eos_coefficient = eos_coefficient + + if not hasattr(self, "d_model"): + self.d_model = d_model + + if not hasattr(self, "encoder_attention_heads"): + self.encoder_attention_heads = encoder_attention_heads + # add the new attributes with the given values or defaults + self.decoder_n_levels = decoder_n_levels + self.decoder_offset_scale = decoder_offset_scale + self.decoder_method = decoder_method + self.tie_word_embeddings = tie_word_embeddings + + super().__init__(is_encoder_decoder=is_encoder_decoder, **kwargs) + + +def multi_scale_deformable_attention_v2( + value: Tensor, + value_spatial_shapes: Tensor, + sampling_locations: Tensor, + attention_weights: Tensor, + num_points_list: list[int], + method="default", +) -> Tensor: + batch_size, _, num_heads, hidden_dim = value.shape + _, num_queries, num_heads, num_levels, num_points = sampling_locations.shape + value_list = ( + value.permute(0, 2, 3, 1) + .flatten(0, 1) + .split([height * width for height, width in value_spatial_shapes], dim=-1) + ) + # sampling_offsets [8, 480, 8, 12, 2] + if method == "default": + sampling_grids = 2 * sampling_locations - 1 + elif method == "discrete": + sampling_grids = sampling_locations + sampling_grids = sampling_grids.permute(0, 2, 1, 3, 4).flatten(0, 1) + sampling_grids = sampling_grids.split(num_points_list, dim=-2) + sampling_value_list = [] + for level_id, (height, width) in enumerate(value_spatial_shapes): + # batch_size, height*width, num_heads, hidden_dim + # -> batch_size, height*width, num_heads*hidden_dim + # -> batch_size, num_heads*hidden_dim, height*width + # -> batch_size*num_heads, hidden_dim, height, width + value_l_ = value_list[level_id].reshape(batch_size * num_heads, hidden_dim, height, width) + # batch_size, num_queries, num_heads, num_points, 2 + # -> batch_size, num_heads, num_queries, num_points, 2 + # -> batch_size*num_heads, num_queries, num_points, 2 + sampling_grid_l_ = sampling_grids[level_id] + # batch_size*num_heads, hidden_dim, num_queries, num_points + if method == "default": + sampling_value_l_ = nn.functional.grid_sample( + value_l_, sampling_grid_l_, mode="bilinear", padding_mode="zeros", align_corners=False + ) + elif method == "discrete": + sampling_coord = (sampling_grid_l_ * torch.tensor([[width, height]], device=value.device) + 0.5).to( + torch.int64 + ) + + # Separate clamping for x and y coordinates + sampling_coord_x = sampling_coord[..., 0].clamp(0, width - 1) + sampling_coord_y = sampling_coord[..., 1].clamp(0, height - 1) + + # Combine the clamped coordinates + sampling_coord = torch.stack([sampling_coord_x, sampling_coord_y], dim=-1) + sampling_coord = sampling_coord.reshape(batch_size * num_heads, num_queries * num_points_list[level_id], 2) + sampling_idx = ( + torch.arange(sampling_coord.shape[0], device=value.device) + .unsqueeze(-1) + .repeat(1, sampling_coord.shape[1]) + ) + sampling_value_l_ = value_l_[sampling_idx, :, sampling_coord[..., 1], sampling_coord[..., 0]] + sampling_value_l_ = sampling_value_l_.permute(0, 2, 1).reshape( + batch_size * num_heads, hidden_dim, num_queries, num_points_list[level_id] + ) + sampling_value_list.append(sampling_value_l_) + # (batch_size, num_queries, num_heads, num_levels, num_points) + # -> (batch_size, num_heads, num_queries, num_levels, num_points) + # -> (batch_size, num_heads, 1, num_queries, num_levels*num_points) + attention_weights = attention_weights.permute(0, 2, 1, 3).reshape( + batch_size * num_heads, 1, num_queries, sum(num_points_list) + ) + output = ( + (torch.concat(sampling_value_list, dim=-1) * attention_weights) + .sum(-1) + .view(batch_size, num_heads * hidden_dim, num_queries) + ) + return output.transpose(1, 2).contiguous() + + +# the main change +class RTDetrV2MultiscaleDeformableAttention(nn.Module): + """ + RTDetrV2 version of multiscale deformable attention, extending the base implementation + with improved offset handling and initialization. + """ + + def __init__(self, config: RTDetrV2Config): + super().__init__() + num_heads = config.decoder_attention_heads + n_points = config.decoder_n_points + + if config.d_model % num_heads != 0: + raise ValueError( + f"embed_dim (d_model) must be divisible by num_heads, but got {config.d_model} and {num_heads}" + ) + dim_per_head = config.d_model // num_heads + # check if dim_per_head is power of 2 + if not ((dim_per_head & (dim_per_head - 1) == 0) and dim_per_head != 0): + warnings.warn( + "You'd better set embed_dim (d_model) in RTDetrV2MultiscaleDeformableAttention to make the" + " dimension of each attention head a power of 2 which is more efficient in the authors' CUDA" + " implementation." + ) + + self.im2col_step = 64 + + self.d_model = config.d_model + + # V2-specific attributes + self.n_levels = config.decoder_n_levels + self.n_heads = num_heads + self.n_points = n_points + + self.sampling_offsets = nn.Linear(config.d_model, num_heads * self.n_levels * n_points * 2) + self.attention_weights = nn.Linear(config.d_model, num_heads * self.n_levels * n_points) + self.value_proj = nn.Linear(config.d_model, config.d_model) + self.output_proj = nn.Linear(config.d_model, config.d_model) + + self.offset_scale = config.decoder_offset_scale + self.method = config.decoder_method + + # Initialize n_points list and scale + n_points_list = [self.n_points for _ in range(self.n_levels)] + self.n_points_list = n_points_list + n_points_scale = [1 / n for n in n_points_list for _ in range(n)] + self.register_buffer("n_points_scale", torch.tensor(n_points_scale, dtype=torch.float32)) + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.Tensor | None = None, + encoder_hidden_states=None, + encoder_attention_mask=None, + position_embeddings: torch.Tensor | None = None, + reference_points=None, + spatial_shapes=None, + spatial_shapes_list=None, + level_start_index=None, + **kwargs: Unpack[TransformersKwargs], + ): + # Process inputs up to sampling locations calculation using parent class logic + if position_embeddings is not None: + hidden_states = hidden_states + position_embeddings + + batch_size, num_queries, _ = hidden_states.shape + batch_size, sequence_length, _ = encoder_hidden_states.shape + torch_compilable_check( + (spatial_shapes[:, 0] * spatial_shapes[:, 1]).sum() == sequence_length, + "Make sure to align the spatial shapes with the sequence length of the encoder hidden states", + ) + + value = self.value_proj(encoder_hidden_states) + if attention_mask is not None: + value = value.masked_fill(~attention_mask[..., None], float(0)) + value = value.view(batch_size, sequence_length, self.n_heads, self.d_model // self.n_heads) + + # V2-specific sampling offsets shape + sampling_offsets = self.sampling_offsets(hidden_states).view( + batch_size, num_queries, self.n_heads, self.n_levels * self.n_points, 2 + ) + + attention_weights = self.attention_weights(hidden_states).view( + batch_size, num_queries, self.n_heads, self.n_levels * self.n_points + ) + attention_weights = F.softmax(attention_weights, -1) + + # V2-specific sampling locations calculation + if reference_points.shape[-1] == 2: + offset_normalizer = torch.stack([spatial_shapes[..., 1], spatial_shapes[..., 0]], -1) + sampling_locations = ( + reference_points[:, :, None, :, None, :] + + sampling_offsets / offset_normalizer[None, None, None, :, None, :] + ) + elif reference_points.shape[-1] == 4: + n_points_scale = self.n_points_scale.to(dtype=hidden_states.dtype).unsqueeze(-1) + offset = sampling_offsets * n_points_scale * reference_points[:, :, None, :, 2:] * self.offset_scale + sampling_locations = reference_points[:, :, None, :, :2] + offset + else: + raise ValueError(f"Last dim of reference_points must be 2 or 4, but got {reference_points.shape[-1]}") + + # V2-specific attention implementation choice + output = multi_scale_deformable_attention_v2( + value, spatial_shapes_list, sampling_locations, attention_weights, self.n_points_list, self.method + ) + + output = self.output_proj(output) + return output, attention_weights + + +class RTDetrV2DecoderLayer(RTDetrDecoderLayer): + def __init__(self, config: RTDetrV2Config): + # initialize parent class + super().__init__(config) + # override only the encoder attention module with v2 version + self.encoder_attn = RTDetrV2MultiscaleDeformableAttention(config) + + +class RTDetrV2PreTrainedModel(RTDetrPreTrainedModel): + def _init_weights(self, module): + super()._init_weights(module) + if isinstance(module, RTDetrV2MultiscaleDeformableAttention): + n_points_scale = [1 / n for n in module.n_points_list for _ in range(n)] + init.copy_(module.n_points_scale, torch.tensor(n_points_scale, dtype=torch.float32)) + + +class RTDetrV2Decoder(RTDetrDecoder): + def __init__(self, config: RTDetrV2Config): + super().__init__(config) + self.layers = nn.ModuleList([RTDetrV2DecoderLayer(config) for _ in range(config.decoder_layers)]) + + +class RTDetrV2Model(RTDetrModel): + def __init__(self, config: RTDetrV2Config): + super().__init__(config) + # decoder + self.decoder = RTDetrV2Decoder(config) + + +class RTDetrV2MLPPredictionHead(RTDetrMLPPredictionHead): + pass + + +class RTDetrV2ForObjectDetection(RTDetrForObjectDetection, RTDetrV2PreTrainedModel): + _tied_weights_keys = { + r"bbox_embed.(?![0])\d+": r"bbox_embed.0", + r"class_embed.(?![0])\d+": r"^class_embed.0", + "class_embed": "model.decoder.class_embed", + "bbox_embed": "model.decoder.bbox_embed", + } + + def __init__(self, config: RTDetrV2Config): + RTDetrV2PreTrainedModel.__init__(self, config) + # RTDETR encoder-decoder model + self.model = RTDetrV2Model(config) + self.class_embed = nn.ModuleList( + [torch.nn.Linear(config.d_model, config.num_labels) for _ in range(config.decoder_layers)] + ) + self.bbox_embed = nn.ModuleList( + [ + RTDetrV2MLPPredictionHead(config.d_model, config.d_model, 4, num_layers=3) + for _ in range(config.decoder_layers) + ] + ) + self.model.decoder.class_embed = self.class_embed + self.model.decoder.bbox_embed = self.bbox_embed + + # Initialize weights and apply final processing + self.post_init() + + +__all__ = [ + "RTDetrV2Config", + "RTDetrV2Model", + "RTDetrV2PreTrainedModel", + "RTDetrV2ForObjectDetection", +] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/rwkv/__init__.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/rwkv/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..cbfdb86827a0f5551fc99ad84edf2c2684444e96 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/rwkv/__init__.py @@ -0,0 +1,27 @@ +# Copyright 2024 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from typing import TYPE_CHECKING + +from ...utils import _LazyModule +from ...utils.import_utils import define_import_structure + + +if TYPE_CHECKING: + from .configuration_rwkv import * + from .modeling_rwkv import * +else: + import sys + + _file = globals()["__file__"] + sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__) diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/rwkv/configuration_rwkv.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/rwkv/configuration_rwkv.py new file mode 100644 index 0000000000000000000000000000000000000000..95711afa8b7cf3244affd69dc13b7d69a35fb953 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/rwkv/configuration_rwkv.py @@ -0,0 +1,118 @@ +# Copyright 2023 The OpenAI Team Authors and HuggingFace Inc. team. +# Copyright (c) 2018, NVIDIA CORPORATION. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""RWKV configuration""" + +from ...configuration_utils import PreTrainedConfig +from ...utils import logging + + +logger = logging.get_logger(__name__) + + +class RwkvConfig(PreTrainedConfig): + """ + This is the configuration class to store the configuration of a [`RwkvModel`]. It is used to instantiate a RWKV + model according to the specified arguments, defining the model architecture. Instantiating a configuration with the + defaults will yield a similar configuration to that of the RWVK-4 + [RWKV/rwkv-4-169m-pile](https://huggingface.co/RWKV/rwkv-4-169m-pile) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + + Args: + vocab_size (`int`, *optional*, defaults to 50277): + Vocabulary size of the RWKV model. Defines the number of different tokens that can be represented by the + `inputs_ids` passed when calling [`RwkvModel`]. + context_length (`int`, *optional*, defaults to 1024): + The maximum sequence length that this model can be used with in a single forward (using it in RNN mode + lets use any sequence length). + hidden_size (`int`, *optional*, defaults to 4096): + Dimensionality of the embeddings and hidden states. + num_hidden_layers (`int`, *optional*, defaults to 32): + Number of hidden layers in the model. + attention_hidden_size (`int`, *optional*): + Dimensionality of the attention hidden states. Will default to `hidden_size` if unset. + intermediate_size (`int`, *optional*): + Dimensionality of the inner feed-forward layers. Will default to 4 times `hidden_size` if unset. + layer_norm_epsilon (`float`, *optional*, defaults to 1e-05): + The epsilon to use in the layer normalization layers. + bos_token_id (`int`, *optional*, defaults to 0): + The id of the beginning of sentence token in the vocabulary. Defaults to 0 as RWKV uses the same tokenizer + as GPTNeoX. + eos_token_id (`int`, *optional*, defaults to 0): + The id of the end of sentence token in the vocabulary. Defaults to 0 as RWKV uses the same tokenizer as + GPTNeoX. + rescale_every (`int`, *optional*, defaults to 6): + At inference, the hidden states (and weights of the corresponding output layers) are divided by 2 every + `rescale_every` layer. If set to 0 or a negative number, no rescale is done. + tie_word_embeddings (`bool`, *optional*, defaults to `False`): + Whether or not to tie the word embeddings with the input token embeddings. + use_cache (`bool`, *optional*, defaults to `True`): + Whether or not the model should return the last state. + + + Example: + + ```python + >>> from transformers import RwkvConfig, RwkvModel + + >>> # Initializing a Rwkv configuration + >>> configuration = RwkvConfig() + + >>> # Initializing a model (with random weights) from the configuration + >>> model = RwkvModel(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "rwkv" + attribute_map = {"max_position_embeddings": "context_length"} + + def __init__( + self, + vocab_size=50277, + context_length=1024, + hidden_size=4096, + num_hidden_layers=32, + attention_hidden_size=None, + intermediate_size=None, + layer_norm_epsilon=1e-5, + bos_token_id=0, + eos_token_id=0, + rescale_every=6, + tie_word_embeddings=False, + use_cache=True, + **kwargs, + ): + self.vocab_size = vocab_size + self.context_length = context_length + self.hidden_size = hidden_size + self.num_hidden_layers = num_hidden_layers + self.attention_hidden_size = attention_hidden_size if attention_hidden_size is not None else hidden_size + self.intermediate_size = intermediate_size if intermediate_size is not None else 4 * hidden_size + self.layer_norm_epsilon = layer_norm_epsilon + self.rescale_every = rescale_every + self.use_cache = use_cache + + self.bos_token_id = bos_token_id + self.eos_token_id = eos_token_id + self.tie_word_embeddings = tie_word_embeddings + + super().__init__(**kwargs) + + +__all__ = ["RwkvConfig"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/rwkv/modeling_rwkv.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/rwkv/modeling_rwkv.py new file mode 100644 index 0000000000000000000000000000000000000000..1234757a9102bb221a35920af0c826defedcf60a --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/rwkv/modeling_rwkv.py @@ -0,0 +1,758 @@ +# Copyright 2023 Bo Peng and HuggingFace Inc. team. +# Copyright (c) 2018, NVIDIA CORPORATION. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""PyTorch RWKV model.""" + +import math +from dataclasses import dataclass + +import torch +from torch import nn + +from ... import initialization as init +from ...generation import GenerationMixin +from ...modeling_layers import GradientCheckpointingLayer +from ...modeling_utils import PreTrainedModel +from ...utils import ( + ModelOutput, + auto_docstring, + is_bitsandbytes_available, + is_kernels_available, + is_ninja_available, + is_torch_cuda_available, + logging, +) +from .configuration_rwkv import RwkvConfig + + +logger = logging.get_logger(__name__) + + +rwkv_cuda_kernel = None + + +def load_wkv_cuda_kernel(context_length): + global rwkv_cuda_kernel + if not is_kernels_available(): + raise ImportError("kernels is not installed, please install it with `pip install kernels`") + + from ...integrations.hub_kernels import get_kernel + + rwkv_cuda_kernel = get_kernel("kernels-community/rwkv") + rwkv_cuda_kernel.max_seq_length = context_length + + +class RwkvLinearAttention(torch.autograd.Function): + @staticmethod + def forward(ctx, time_decay, time_first, key, value, state=None, return_state=False): + batch_size, seq_len, hidden_size = key.size() + if seq_len > rwkv_cuda_kernel.max_seq_length: + raise ValueError( + f"Cannot process a batch with {seq_len} tokens at the same time, use a maximum of " + f"{rwkv_cuda_kernel.max_seq_length} with this model." + ) + if batch_size * hidden_size % min(hidden_size, 32) != 0: + raise ValueError( + f"The product of batch size ({batch_size}) and hidden size ({hidden_size}) needs to be a round " + f"multiple of {min(hidden_size, 32)}." + ) + + ctx.input_dtype = key.dtype + + if ( + time_decay.device.type != "cuda" + or time_first.device.type != "cuda" + or key.device.type != "cuda" + or value.device.type != "cuda" + ): + raise ValueError("Calling the CUDA kernel for wkv attention requires all tensors to be on CUDA devices.") + + time_decay = -torch.exp(time_decay.float().contiguous()) + if key.dtype == torch.float16: + time_first = time_first.float() + key = key.float() + value = value.float() + time_first = time_first.contiguous() + key = key.contiguous() + value = value.contiguous() + # The CUDA kernel will fill this tensor. + output = torch.empty_like(key, memory_format=torch.contiguous_format) + if return_state or state is not None: + if state is None: + state = torch.zeros( + batch_size, + hidden_size, + 3, + dtype=torch.float32, + device=key.device, + memory_format=torch.contiguous_format, + ) + state[:, :, 2] -= 1e38 + else: + state = torch.cat([s.unsqueeze(2) for s in state], dim=2).contiguous() + if key.dtype == torch.bfloat16: + forward_func = rwkv_cuda_kernel.forward_with_state_bf16 + else: + forward_func = rwkv_cuda_kernel.forward_with_state + forward_func(time_decay, time_first, key, value, output, state) + else: + forward_func = rwkv_cuda_kernel.forward_bf16 if key.dtype == torch.bfloat16 else rwkv_cuda_kernel.forward + forward_func(time_decay, time_first, key, value, output) + + ctx.save_for_backward(time_decay, time_first, key, value, output) + + if state is not None: + state = [s.squeeze(2) for s in torch.chunk(state, 3, dim=2)] + + return output.to(ctx.input_dtype), state + + @staticmethod + # g stands for grad + def backward(ctx, g_output, g_state=None): + input_dtype = ctx.input_dtype + + time_decay, time_first, key, value, output = ctx.saved_tensors + # The CUDA kernel will fill those tensors. + g_time_decay = torch.empty_like( + time_decay, + memory_format=torch.contiguous_format, + dtype=torch.bfloat16 if input_dtype == torch.bfloat16 else torch.float32, + ) + g_time_first = torch.empty_like(time_first, memory_format=torch.contiguous_format) + g_key = torch.empty_like(key, memory_format=torch.contiguous_format) + g_value = torch.empty_like(value, memory_format=torch.contiguous_format) + + if input_dtype == torch.float16: + g_output = g_output.float() + backward_func = rwkv_cuda_kernel.backward_bf16 if input_dtype == torch.bfloat16 else rwkv_cuda_kernel.backward + backward_func( + time_decay, + time_first, + key, + value, + output, + g_output.contiguous(), + g_time_decay, + g_time_first, + g_key, + g_value, + ) + + return ( + g_time_decay.to(input_dtype), + g_time_first.to(input_dtype), + g_key.to(input_dtype), + g_value.to(input_dtype), + None, + None, + ) + + +def rwkv_linear_attention_cpu(time_decay, time_first, key, value, state=None, return_state=False): + # For CPU fallback. Will be slower and probably take more memory than the custom CUDA kernel if not executed + # within a torch.no_grad. + _, seq_length, _ = key.size() + output = torch.zeros_like(key) + + if state is None: + num_state = torch.zeros_like(key[:, 0], dtype=torch.float32) + den_state = torch.zeros_like(key[:, 0], dtype=torch.float32) + max_state = torch.zeros_like(key[:, 0], dtype=torch.float32) - 1e38 + else: + num_state, den_state, max_state = state + # For numerical stability + # real_numerator_state = num_state * torch.exp(max_state) + # real_denominator_state = den_state * torch.exp(max_state) + + time_decay = -torch.exp(time_decay) + + for current_index in range(seq_length): + current_key = key[:, current_index].float() + current_value = value[:, current_index] + + # wkv computation at time t + max_for_output = torch.maximum(max_state, current_key + time_first) + e1 = torch.exp(max_state - max_for_output) + e2 = torch.exp(current_key + time_first - max_for_output) + numerator = e1 * num_state + e2 * current_value + denominator = e1 * den_state + e2 + output[:, current_index] = (numerator / denominator).to(output.dtype) + + # Update state for next iteration + max_for_state = torch.maximum(max_state + time_decay, current_key) + e1 = torch.exp(max_state + time_decay - max_for_state) + e2 = torch.exp(current_key - max_for_state) + num_state = e1 * num_state + e2 * current_value + den_state = e1 * den_state + e2 + max_state = max_for_state + + if return_state or state is not None: + state = [num_state, den_state, max_state] + + return output, state + + +def rwkv_linear_attention(time_decay, time_first, key, value, state=None, return_state=False): + no_cuda = any(t.device.type != "cuda" for t in [time_decay, time_first, key, value]) + # Launching the CUDA kernel for just one token will actually be slower (there is no for loop in the CPU version + # in this case). + one_token = key.size(1) == 1 + if rwkv_cuda_kernel is None or no_cuda or one_token: + return rwkv_linear_attention_cpu(time_decay, time_first, key, value, state=state, return_state=return_state) + else: + return RwkvLinearAttention.apply(time_decay, time_first, key, value, state, return_state) + + +class RwkvSelfAttention(nn.Module): + def __init__(self, config, layer_id=0): + super().__init__() + self.config = config + kernel_loaded = rwkv_cuda_kernel is not None and rwkv_cuda_kernel.max_seq_length == config.context_length + if is_ninja_available() and is_torch_cuda_available() and not kernel_loaded: + try: + load_wkv_cuda_kernel(config.context_length) + except Exception: + logger.info("Could not load the custom CUDA kernel for RWKV attention.") + self.layer_id = layer_id + hidden_size = config.hidden_size + attention_hidden_size = ( + config.attention_hidden_size if config.attention_hidden_size is not None else hidden_size + ) + self.attention_hidden_size = attention_hidden_size + + self.time_decay = nn.Parameter(torch.empty(attention_hidden_size)) + self.time_first = nn.Parameter(torch.empty(attention_hidden_size)) + + self.time_mix_key = nn.Parameter(torch.empty(1, 1, hidden_size)) + self.time_mix_value = nn.Parameter(torch.empty(1, 1, hidden_size)) + self.time_mix_receptance = nn.Parameter(torch.empty(1, 1, hidden_size)) + + self.time_shift = nn.ZeroPad2d((0, 0, 1, -1)) + self.key = nn.Linear(hidden_size, attention_hidden_size, bias=False) + self.value = nn.Linear(hidden_size, attention_hidden_size, bias=False) + self.receptance = nn.Linear(hidden_size, attention_hidden_size, bias=False) + self.output = nn.Linear(attention_hidden_size, hidden_size, bias=False) + + # TODO: maybe jit, otherwise move inside forward + def extract_key_value(self, hidden, state=None): + # Mix hidden with the previous timestep to produce key, value, receptance + if hidden.size(1) == 1 and state is not None: + shifted = state[1][:, :, self.layer_id] + else: + shifted = self.time_shift(hidden) + if state is not None: + shifted[:, 0] = state[1][:, :, self.layer_id] + key = hidden * self.time_mix_key + shifted * (1 - self.time_mix_key) + value = hidden * self.time_mix_value + shifted * (1 - self.time_mix_value) + receptance = hidden * self.time_mix_receptance + shifted * (1 - self.time_mix_receptance) + + key = self.key(key) + value = self.value(value) + receptance = torch.sigmoid(self.receptance(receptance)) + if state is not None: + state[1][:, :, self.layer_id] = hidden[:, -1] + return receptance, key, value, state + + def forward(self, hidden, state=None, use_cache=False): + receptance, key, value, state = self.extract_key_value(hidden, state=state) + layer_state = tuple(s[:, :, self.layer_id] for s in state[2:]) if state is not None else None + rwkv, layer_state = rwkv_linear_attention( + self.time_decay, + self.time_first, + key, + value, + state=layer_state, + return_state=use_cache, + ) + + if layer_state is not None: + state[2][:, :, self.layer_id] = layer_state[0] + state[3][:, :, self.layer_id] = layer_state[1] + state[4][:, :, self.layer_id] = layer_state[2] + + return self.output(receptance * rwkv), state + + +class RwkvFeedForward(nn.Module): + def __init__(self, config, layer_id=0): + super().__init__() + self.config = config + self.layer_id = layer_id + hidden_size = config.hidden_size + intermediate_size = ( + config.intermediate_size if config.intermediate_size is not None else 4 * config.hidden_size + ) + + self.time_shift = nn.ZeroPad2d((0, 0, 1, -1)) + self.time_mix_key = nn.Parameter(torch.empty(1, 1, hidden_size)) + self.time_mix_receptance = nn.Parameter(torch.empty(1, 1, hidden_size)) + + self.key = nn.Linear(hidden_size, intermediate_size, bias=False) + self.receptance = nn.Linear(hidden_size, hidden_size, bias=False) + self.value = nn.Linear(intermediate_size, hidden_size, bias=False) + + def forward(self, hidden, state=None): + if hidden.size(1) == 1 and state is not None: + shifted = state[0][:, :, self.layer_id] + else: + shifted = self.time_shift(hidden) + if state is not None: + shifted[:, 0] = state[0][:, :, self.layer_id] + key = hidden * self.time_mix_key + shifted * (1 - self.time_mix_key) + receptance = hidden * self.time_mix_receptance + shifted * (1 - self.time_mix_receptance) + + key = torch.square(torch.relu(self.key(key))) + value = self.value(key) + receptance = torch.sigmoid(self.receptance(receptance)) + + if state is not None: + state[0][:, :, self.layer_id] = hidden[:, -1] + + return receptance * value, state + + +class RwkvBlock(GradientCheckpointingLayer): + def __init__(self, config, layer_id): + super().__init__() + self.config = config + self.layer_id = layer_id + + if layer_id == 0: + self.pre_ln = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_epsilon) + + self.ln1 = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_epsilon) + self.ln2 = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_epsilon) + + self.attention = RwkvSelfAttention(config, layer_id) + self.feed_forward = RwkvFeedForward(config, layer_id) + + def forward(self, hidden, state=None, use_cache=False, output_attentions=False): + if self.layer_id == 0: + hidden = self.pre_ln(hidden) + + attention, state = self.attention(self.ln1(hidden), state=state, use_cache=use_cache) + hidden = hidden + attention + + feed_forward, state = self.feed_forward(self.ln2(hidden), state=state) + hidden = hidden + feed_forward + + outputs = (hidden, state) + if output_attentions: + outputs += (attention,) + else: + outputs += (None,) + + return outputs + + +@auto_docstring +class RwkvPreTrainedModel(PreTrainedModel): + config: RwkvConfig + base_model_prefix = "rwkv" + _no_split_modules = ["RwkvBlock"] + _keep_in_fp32_modules = ["time_decay", "time_first"] + supports_gradient_checkpointing = True + _is_stateful = True + + @torch.no_grad() + def _init_weights(self, module: nn.Module): + """Initialize the weights.""" + if isinstance(module, RwkvSelfAttention): + layer_id = module.layer_id + num_hidden_layers = module.config.num_hidden_layers + hidden_size = module.config.hidden_size + attention_hidden_size = module.attention_hidden_size + + ratio_0_to_1 = layer_id / (num_hidden_layers - 1) # 0 to 1 + ratio_1_to_almost0 = 1.0 - (layer_id / num_hidden_layers) # 1 to ~0 + + time_weight = torch.tensor( + [i / hidden_size for i in range(hidden_size)], + dtype=module.time_mix_key.dtype, + device=module.time_mix_key.device, + ) + time_weight = time_weight[None, None, :] + + decay_speed = [ + -5 + 8 * (h / (attention_hidden_size - 1)) ** (0.7 + 1.3 * ratio_0_to_1) + for h in range(attention_hidden_size) + ] + decay_speed = torch.tensor(decay_speed, dtype=module.time_decay.dtype, device=module.time_decay.device) + zigzag = ( + torch.tensor( + [(i + 1) % 3 - 1 for i in range(attention_hidden_size)], + dtype=module.time_first.dtype, + device=module.time_first.device, + ) + * 0.5 + ) + + init.copy_(module.time_decay, decay_speed) + init.copy_(module.time_first, torch.ones_like(module.time_first * math.log(0.3) + zigzag)) + + init.copy_(module.time_mix_key, torch.pow(time_weight, ratio_1_to_almost0)) + init.copy_(module.time_mix_value, torch.pow(time_weight, ratio_1_to_almost0) + 0.3 * ratio_0_to_1) + init.copy_(module.time_mix_receptance, torch.pow(time_weight, 0.5 * ratio_1_to_almost0)) + elif isinstance(module, RwkvFeedForward): + layer_id = module.layer_id + num_hidden_layers = module.config.num_hidden_layers + hidden_size = module.config.hidden_size + + ratio_1_to_almost0 = 1.0 - (layer_id / num_hidden_layers) # 1 to ~0 + + time_weight = torch.tensor( + [i / hidden_size for i in range(hidden_size)], + dtype=module.time_mix_key.dtype, + device=module.time_mix_key.device, + ) + time_weight = time_weight[None, None, :] + + init.copy_(module.time_mix_key, torch.pow(time_weight, ratio_1_to_almost0)) + init.copy_(module.time_mix_receptance, torch.pow(time_weight, ratio_1_to_almost0)) + elif isinstance(module, nn.Linear): + shape = module.weight.shape + gain = 1.0 + scale = 1.0 # extra scale for gain + if module.bias is not None: + init.zeros_(module.bias) + if shape[0] > shape[1]: + gain = math.sqrt(shape[0] / shape[1]) + if shape[0] == self.config.vocab_size and shape[1] == self.config.hidden_size: # final projection? + scale = 0.5 + + gain *= scale + init.orthogonal_(module.weight, gain=gain) + elif isinstance(module, nn.Embedding): + shape = module.weight.shape + gain = 1e-4 * math.sqrt(max(shape[0], shape[1])) + init.orthogonal_(module.weight, gain=gain) + elif isinstance(module, nn.LayerNorm): + init.ones_(module.weight) + init.zeros_(module.bias) + + +@dataclass +@auto_docstring( + custom_intro=""" + Class for the RWKV model outputs. + """ +) +class RwkvOutput(ModelOutput): + r""" + state (list of five `torch.FloatTensor` of shape `(batch_size, hidden_size, num_hidden_layers)`): + The state of the model at the last time step. Can be used in a forward method with the next `input_ids` to + avoid providing the old `input_ids`. + """ + + last_hidden_state: torch.FloatTensor | None = None + state: list[torch.FloatTensor] | None = None + hidden_states: tuple[torch.FloatTensor, ...] | None = None + attentions: tuple[torch.FloatTensor, ...] | None = None + + +@dataclass +@auto_docstring( + custom_intro=""" + Base class for causal language model (or autoregressive) outputs. + """ +) +class RwkvCausalLMOutput(ModelOutput): + r""" + loss (`torch.FloatTensor` of shape `(1,)`, *optional*, returned when `labels` is provided): + Language modeling loss (for next-token prediction). + logits (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.vocab_size)`): + Prediction scores of the language modeling head (scores for each vocabulary token before SoftMax). + state (list of five `torch.FloatTensor` of shape `(batch_size, hidden_size, num_hidden_layers)`): + The state of the model at the last time step. Can be used in a forward method with the next `input_ids` to + avoid providing the old `input_ids`. + """ + + loss: torch.FloatTensor | None = None + logits: torch.FloatTensor | None = None + state: list[torch.FloatTensor] | None = None + hidden_states: tuple[torch.FloatTensor, ...] | None = None + attentions: tuple[torch.FloatTensor, ...] | None = None + + +@auto_docstring +class RwkvModel(RwkvPreTrainedModel): + def __init__(self, config): + super().__init__(config) + + self.embeddings = nn.Embedding(config.vocab_size, config.hidden_size) + self.blocks = nn.ModuleList([RwkvBlock(config, layer_id=idx) for idx in range(config.num_hidden_layers)]) + self.ln_out = nn.LayerNorm(config.hidden_size) + + self.layers_are_rescaled = False + + self.gradient_checkpointing = False + + # Initialize weights and apply final processing + self.post_init() + + def get_input_embeddings(self): + return self.embeddings + + def set_input_embeddings(self, new_embeddings): + self.embeddings = new_embeddings + + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.LongTensor | None = None, + inputs_embeds: torch.FloatTensor | None = None, + state: list[torch.FloatTensor] | None = None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + **kwargs, + ) -> tuple | RwkvOutput: + r""" + input_ids (`torch.LongTensor` of shape `(batch_size, input_ids_length)`): + `input_ids_length` = `sequence_length` if `past_key_values` is `None` else + `past_key_values.get_seq_length()` (`sequence_length` of input past key value states). Indices of input + sequence tokens in the vocabulary. + + If `past_key_values` is used, only `input_ids` that do not have their past calculated should be passed as + `input_ids`. + + Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and + [`PreTrainedTokenizer.__call__`] for details. + + [What are input IDs?](../glossary#input-ids) + state (tuple of five `torch.FloatTensor` of shape `(batch_size, hidden_size, num_hidden_layers)`, *optional*): + If passed along, the model uses the previous state in all the blocks (which will give the output for the + `input_ids` provided as if the model add `state_input_ids + input_ids` as context). + use_cache (`bool`, *optional*): + If set to `True`, the last state is returned and can be used to quickly generate the next logits. + """ + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + use_cache = use_cache if use_cache is not None else (self.config.use_cache if not self.training else False) + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + if attention_mask is not None: + logger.warning_once("`attention_mask` was passed, but it is unused in this model.") + + if self.training == self.layers_are_rescaled: + self._rescale_layers() + + if input_ids is not None and inputs_embeds is not None: + raise ValueError("You cannot specify both input_ids and inputs_embeds at the same time") + elif input_ids is None and inputs_embeds is None: + raise ValueError("You have to specify either input_ids or inputs_embeds") + + if inputs_embeds is None: + inputs_embeds = self.embeddings(input_ids) + + if use_cache and state is None: + shape = (inputs_embeds.size(0), self.config.hidden_size, self.config.num_hidden_layers) + state = [ + torch.zeros( + *shape, dtype=inputs_embeds.dtype if i <= 1 else torch.float32, device=inputs_embeds.device + ) + for i in range(5) + ] + state[4] -= 1e30 + + if self.gradient_checkpointing and self.training: + if use_cache: + logger.warning_once( + "`use_cache=True` is incompatible with gradient checkpointing. Setting `use_cache=False`..." + ) + use_cache = False + + hidden_states = inputs_embeds + + all_self_attentions = () if output_attentions else None + all_hidden_states = () if output_hidden_states else None + for idx, block in enumerate(self.blocks): + hidden_states, state, attentions = block( + hidden_states, state=state, use_cache=use_cache, output_attentions=output_attentions + ) + + if ( + self.layers_are_rescaled + and self.config.rescale_every > 0 + and (idx + 1) % self.config.rescale_every == 0 + ): + hidden_states = hidden_states / 2 + + if output_hidden_states: + all_hidden_states = all_hidden_states + (hidden_states,) + + if output_attentions: + all_self_attentions = all_self_attentions + (attentions,) + + hidden_states = self.ln_out(hidden_states) + + if output_hidden_states: + all_hidden_states = all_hidden_states + (hidden_states,) + + if not return_dict: + return tuple(x for x in [hidden_states, state, all_hidden_states, all_self_attentions] if x is not None) + + return RwkvOutput( + last_hidden_state=hidden_states, + state=state, + hidden_states=all_hidden_states, + attentions=all_self_attentions, + ) + + def _rescale_layers(self): + # Layers should be rescaled for inference only. + if self.layers_are_rescaled == (not self.training): + return + if self.config.rescale_every > 0: + with torch.no_grad(): + for block_id, block in enumerate(self.blocks): + if self.training: + block.attention.output.weight.mul_(2 ** int(block_id // self.config.rescale_every)) + block.feed_forward.value.weight.mul_(2 ** int(block_id // self.config.rescale_every)) + else: + # Deal with quantization statistics + if hasattr(block.attention.output.weight, "SCB"): + block.attention.output.weight.SCB.div_(2 ** int(block_id // self.config.rescale_every)) + block.feed_forward.value.weight.SCB.div_(2 ** int(block_id // self.config.rescale_every)) + elif hasattr(block.attention.output.weight, "quant_state"): + self._bnb_4bit_dequantize_and_rescale(block.attention.output, block_id) + self._bnb_4bit_dequantize_and_rescale(block.feed_forward.value, block_id) + else: + block.attention.output.weight.div_(2 ** int(block_id // self.config.rescale_every)) + block.feed_forward.value.weight.div_(2 ** int(block_id // self.config.rescale_every)) + + self.layers_are_rescaled = not self.training + + def _bnb_4bit_dequantize_and_rescale(self, target_layer, block_id): + r""" + Perform the dequantization and rescaling of the weights of a given layer. After that operation the layer will + be quantized again. + """ + if not is_bitsandbytes_available(): + raise ImportError("Please install bitsandbytes to use this method.") + import bitsandbytes as bnb + + dequant_weights = bnb.functional.dequantize_4bit(target_layer.weight.data, target_layer.weight.quant_state) + + dequant_weights.div_(2 ** int(block_id // self.config.rescale_every)) + + # re-quantize the model: + # we need to put it first on CPU then back to the device + # this will create an overhead :/ + # We set requires_grad=False as we cannot compute gradients on top of 4bit parameters anyway and to avoid + # bugs with bnb + quant_weight = bnb.nn.Params4bit(dequant_weights.to("cpu"), requires_grad=False).to(dequant_weights.device) + setattr(target_layer, "weight", quant_weight) + + +@auto_docstring( + custom_intro=""" + The RWKV Model transformer with a language modeling head on top (linear layer with weights tied to the input + embeddings). + """ +) +class RwkvForCausalLM(RwkvPreTrainedModel, GenerationMixin): + _tied_weights_keys = {"head.weight": "rwkv.embeddings.weight"} + + def __init__(self, config): + super().__init__(config) + self.rwkv = RwkvModel(config) + self.head = nn.Linear(config.hidden_size, config.vocab_size, bias=False) + + # Initialize weights and apply final processing + self.post_init() + + def get_output_embeddings(self): + return self.head + + def set_output_embeddings(self, new_embeddings): + self.head = new_embeddings + + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.LongTensor | None = None, + inputs_embeds: torch.FloatTensor | None = None, + state: list[torch.FloatTensor] | None = None, + labels: torch.LongTensor | None = None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + logits_to_keep: int | torch.Tensor = 0, + **kwargs, + ) -> tuple | RwkvCausalLMOutput: + r""" + input_ids (`torch.LongTensor` of shape `(batch_size, input_ids_length)`): + `input_ids_length` = `sequence_length` if `past_key_values` is `None` else + `past_key_values.get_seq_length()` (`sequence_length` of input past key value states). Indices of input + sequence tokens in the vocabulary. + + If `past_key_values` is used, only `input_ids` that do not have their past calculated should be passed as + `input_ids`. + + Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and + [`PreTrainedTokenizer.__call__`] for details. + + [What are input IDs?](../glossary#input-ids) + state (tuple of five `torch.FloatTensor` of shape `(batch_size, hidden_size, num_hidden_layers)`, *optional*): + If passed along, the model uses the previous state in all the blocks (which will give the output for the + `input_ids` provided as if the model add `state_input_ids + input_ids` as context). + labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Labels for language modeling. Note that the labels **are shifted** inside the model, i.e. you can set + `labels = input_ids` Indices are selected in `[-100, 0, ..., config.vocab_size]` All labels set to `-100` + are ignored (masked), the loss is only computed for labels in `[0, ..., config.vocab_size]` + use_cache (`bool`, *optional*): + If set to `True`, the last state is returned and can be used to quickly generate the next logits. + """ + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + rwkv_outputs = self.rwkv( + input_ids, + inputs_embeds=inputs_embeds, + state=state, + use_cache=use_cache, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + + hidden_states = rwkv_outputs[0] + # Only compute necessary logits, and do not upcast them to float if we are not computing the loss + slice_indices = slice(-logits_to_keep, None) if isinstance(logits_to_keep, int) else logits_to_keep + logits = self.head(hidden_states[:, slice_indices, :]) + + loss = None + if labels is not None: + loss = self.loss_function(logits=logits, labels=labels, vocab_size=self.config.vocab_size, **kwargs) + + if not return_dict: + output = (logits,) + rwkv_outputs[1:] + return ((loss,) + output) if loss is not None else output + + return RwkvCausalLMOutput( + loss=loss, + logits=logits, + state=rwkv_outputs.state, + hidden_states=rwkv_outputs.hidden_states, + attentions=rwkv_outputs.attentions, + ) + + +__all__ = ["RwkvForCausalLM", "RwkvModel", "RwkvPreTrainedModel"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam/__init__.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..ac0a21f82930d64e69e4680328ac6d5fe14f38df --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam/__init__.py @@ -0,0 +1,30 @@ +# Copyright 2024 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from typing import TYPE_CHECKING + +from ...utils import _LazyModule +from ...utils.import_utils import define_import_structure + + +if TYPE_CHECKING: + from .configuration_sam import * + from .image_processing_sam import * + from .image_processing_sam_fast import * + from .modeling_sam import * + from .processing_sam import * +else: + import sys + + _file = globals()["__file__"] + sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__) diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam/configuration_sam.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam/configuration_sam.py new file mode 100644 index 0000000000000000000000000000000000000000..f50fbc4dae72eb23e0b57ae515f182f69b63fd14 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam/configuration_sam.py @@ -0,0 +1,339 @@ +# Copyright 2023 The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""SAM model configuration""" + +from ...configuration_utils import PreTrainedConfig +from ...utils import logging + + +logger = logging.get_logger(__name__) + + +class SamPromptEncoderConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`SamPromptEncoder`]. The [`SamPromptEncoder`] + module is used to encode the input 2D points and bounding boxes. Instantiating a configuration defaults will yield + a similar configuration to that of the SAM-vit-h + [facebook/sam-vit-huge](https://huggingface.co/facebook/sam-vit-huge) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + hidden_size (`int`, *optional*, defaults to 256): + Dimensionality of the hidden states. + image_size (`int`, *optional*, defaults to 1024): + The expected output resolution of the image. + patch_size (`int`, *optional*, defaults to 16): + The size (resolution) of each patch. + mask_input_channels (`int`, *optional*, defaults to 16): + The number of channels to be fed to the `MaskDecoder` module. + num_point_embeddings (`int`, *optional*, defaults to 4): + The number of point embeddings to be used. + hidden_act (`str`, *optional*, defaults to `"gelu"`): + The non-linear activation function in the encoder and pooler. + """ + + base_config_key = "prompt_encoder_config" + + def __init__( + self, + hidden_size=256, + image_size=1024, + patch_size=16, + mask_input_channels=16, + num_point_embeddings=4, + hidden_act="gelu", + layer_norm_eps=1e-6, + **kwargs, + ): + super().__init__(**kwargs) + self.hidden_size = hidden_size + self.image_size = image_size + self.patch_size = patch_size + self.image_embedding_size = image_size // patch_size + self.mask_input_channels = mask_input_channels + self.num_point_embeddings = num_point_embeddings + self.hidden_act = hidden_act + self.layer_norm_eps = layer_norm_eps + + +class SamMaskDecoderConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`SamMaskDecoder`]. It is used to instantiate a SAM + mask decoder to the specified arguments, defining the model architecture. Instantiating a configuration defaults + will yield a similar configuration to that of the SAM-vit-h + [facebook/sam-vit-huge](https://huggingface.co/facebook/sam-vit-huge) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + hidden_size (`int`, *optional*, defaults to 256): + Dimensionality of the hidden states. + hidden_act (`str`, *optional*, defaults to `"relu"`): + The non-linear activation function used inside the `SamMaskDecoder` module. + mlp_dim (`int`, *optional*, defaults to 2048): + Dimensionality of the "intermediate" (i.e., feed-forward) layer in the Transformer encoder. + num_hidden_layers (`int`, *optional*, defaults to 2): + Number of hidden layers in the Transformer encoder. + num_attention_heads (`int`, *optional*, defaults to 8): + Number of attention heads for each attention layer in the Transformer encoder. + attention_downsample_rate (`int`, *optional*, defaults to 2): + The downsampling rate of the attention layer. + num_multimask_outputs (`int`, *optional*, defaults to 3): + The number of outputs from the `SamMaskDecoder` module. In the Segment Anything paper, this is set to 3. + iou_head_depth (`int`, *optional*, defaults to 3): + The number of layers in the IoU head module. + iou_head_hidden_dim (`int`, *optional*, defaults to 256): + The dimensionality of the hidden states in the IoU head module. + layer_norm_eps (`float`, *optional*, defaults to 1e-06): + The epsilon used by the layer normalization layers. + + """ + + base_config_key = "mask_decoder_config" + + def __init__( + self, + hidden_size=256, + hidden_act="relu", + mlp_dim=2048, + num_hidden_layers=2, + num_attention_heads=8, + attention_downsample_rate=2, + num_multimask_outputs=3, + iou_head_depth=3, + iou_head_hidden_dim=256, + layer_norm_eps=1e-6, + **kwargs, + ): + super().__init__(**kwargs) + self.hidden_size = hidden_size + self.hidden_act = hidden_act + self.mlp_dim = mlp_dim + self.num_hidden_layers = num_hidden_layers + self.num_attention_heads = num_attention_heads + self.attention_downsample_rate = attention_downsample_rate + self.num_multimask_outputs = num_multimask_outputs + self.iou_head_depth = iou_head_depth + self.iou_head_hidden_dim = iou_head_hidden_dim + self.layer_norm_eps = layer_norm_eps + + +class SamVisionConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`SamVisionModel`]. It is used to instantiate a SAM + vision encoder according to the specified arguments, defining the model architecture. Instantiating a configuration + defaults will yield a similar configuration to that of the SAM ViT-h + [facebook/sam-vit-huge](https://huggingface.co/facebook/sam-vit-huge) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + hidden_size (`int`, *optional*, defaults to 768): + Dimensionality of the encoder layers and the pooler layer. + output_channels (`int`, *optional*, defaults to 256): + Dimensionality of the output channels in the Patch Encoder. + num_hidden_layers (`int`, *optional*, defaults to 12): + Number of hidden layers in the Transformer encoder. + num_attention_heads (`int`, *optional*, defaults to 12): + Number of attention heads for each attention layer in the Transformer encoder. + num_channels (`int`, *optional*, defaults to 3): + Number of channels in the input image. + image_size (`int`, *optional*, defaults to 1024): + Expected resolution. Target size of the resized input image. + patch_size (`int`, *optional*, defaults to 16): + Size of the patches to be extracted from the input image. + hidden_act (`str`, *optional*, defaults to `"gelu"`): + The non-linear activation function (function or string) + layer_norm_eps (`float`, *optional*, defaults to 1e-06): + The epsilon used by the layer normalization layers. + attention_dropout (`float`, *optional*, defaults to 0.0): + The dropout ratio for the attention probabilities. + initializer_range (`float`, *optional*, defaults to 1e-10): + The standard deviation of the truncated_normal_initializer for initializing all weight matrices. + qkv_bias (`bool`, *optional*, defaults to `True`): + Whether to add a bias to query, key, value projections. + mlp_ratio (`float`, *optional*, defaults to 4.0): + Ratio of mlp hidden dim to embedding dim. + use_abs_pos (`bool`, *optional*, defaults to `True`): + Whether to use absolute position embedding. + use_rel_pos (`bool`, *optional*, defaults to `True`): + Whether to use relative position embedding. + window_size (`int`, *optional*, defaults to 14): + Window size for relative position. + global_attn_indexes (`list[int]`, *optional*, defaults to `[2, 5, 8, 11]`): + The indexes of the global attention layers. + num_pos_feats (`int`, *optional*, defaults to 128): + The dimensionality of the position embedding. + mlp_dim (`int`, *optional*): + The dimensionality of the MLP layer in the Transformer encoder. If `None`, defaults to `mlp_ratio * + hidden_size`. + + Example: + + ```python + >>> from transformers import ( + ... SamVisionConfig, + ... SamVisionModel, + ... ) + + >>> # Initializing a SamVisionConfig with `"facebook/sam-vit-huge"` style configuration + >>> configuration = SamVisionConfig() + + >>> # Initializing a SamVisionModel (with random weights) from the `"facebook/sam-vit-huge"` style configuration + >>> model = SamVisionModel(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + base_config_key = "vision_config" + model_type = "sam_vision_model" + + def __init__( + self, + hidden_size=768, + output_channels=256, + num_hidden_layers=12, + num_attention_heads=12, + num_channels=3, + image_size=1024, + patch_size=16, + hidden_act="gelu", + layer_norm_eps=1e-06, + attention_dropout=0.0, + initializer_range=1e-10, + qkv_bias=True, + mlp_ratio=4.0, + use_abs_pos=True, + use_rel_pos=True, + window_size=14, + global_attn_indexes=[2, 5, 8, 11], + num_pos_feats=128, + mlp_dim=None, + **kwargs, + ): + super().__init__(**kwargs) + + self.hidden_size = hidden_size + self.output_channels = output_channels + self.num_hidden_layers = num_hidden_layers + self.num_attention_heads = num_attention_heads + self.num_channels = num_channels + self.image_size = image_size + self.patch_size = patch_size + self.hidden_act = hidden_act + self.layer_norm_eps = layer_norm_eps + self.attention_dropout = attention_dropout + self.initializer_range = initializer_range + self.qkv_bias = qkv_bias + self.mlp_ratio = mlp_ratio + self.use_abs_pos = use_abs_pos + self.use_rel_pos = use_rel_pos + self.window_size = window_size + self.global_attn_indexes = global_attn_indexes + self.num_pos_feats = num_pos_feats + self.mlp_dim = int(hidden_size * mlp_ratio) if mlp_dim is None else mlp_dim + self.scale = self.hidden_size // 2 + + +class SamConfig(PreTrainedConfig): + r""" + [`SamConfig`] is the configuration class to store the configuration of a [`SamModel`]. It is used to instantiate a + SAM model according to the specified arguments, defining the vision model, prompt-encoder model and mask decoder + configs. Instantiating a configuration with the defaults will yield a similar configuration to that of the + SAM-ViT-H [facebook/sam-vit-huge](https://huggingface.co/facebook/sam-vit-huge) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + vision_config (Union[`dict`, `SamVisionConfig`], *optional*): + Dictionary of configuration options used to initialize [`SamVisionConfig`]. + prompt_encoder_config (Union[`dict`, `SamPromptEncoderConfig`], *optional*): + Dictionary of configuration options used to initialize [`SamPromptEncoderConfig`]. + mask_decoder_config (Union[`dict`, `SamMaskDecoderConfig`], *optional*): + Dictionary of configuration options used to initialize [`SamMaskDecoderConfig`]. + + kwargs (*optional*): + Dictionary of keyword arguments. + + Example: + + ```python + >>> from transformers import ( + ... SamVisionConfig, + ... SamPromptEncoderConfig, + ... SamMaskDecoderConfig, + ... SamModel, + ... ) + + >>> # Initializing a SamConfig with `"facebook/sam-vit-huge"` style configuration + >>> configuration = SamConfig() + + >>> # Initializing a SamModel (with random weights) from the `"facebook/sam-vit-huge"` style configuration + >>> model = SamModel(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + + >>> # We can also initialize a SamConfig from a SamVisionConfig, SamPromptEncoderConfig, and SamMaskDecoderConfig + + >>> # Initializing SAM vision, SAM Q-Former and language model configurations + >>> vision_config = SamVisionConfig() + >>> prompt_encoder_config = SamPromptEncoderConfig() + >>> mask_decoder_config = SamMaskDecoderConfig() + + >>> config = SamConfig(vision_config, prompt_encoder_config, mask_decoder_config) + ```""" + + model_type = "sam" + sub_configs = { + "prompt_encoder_config": SamPromptEncoderConfig, + "mask_decoder_config": SamMaskDecoderConfig, + "vision_config": SamVisionConfig, + } + + def __init__( + self, + vision_config=None, + prompt_encoder_config=None, + mask_decoder_config=None, + initializer_range=0.02, + tie_word_embeddings=True, + **kwargs, + ): + vision_config = vision_config if vision_config is not None else {} + prompt_encoder_config = prompt_encoder_config if prompt_encoder_config is not None else {} + mask_decoder_config = mask_decoder_config if mask_decoder_config is not None else {} + + if isinstance(vision_config, SamVisionConfig): + vision_config = vision_config.to_dict() + if isinstance(prompt_encoder_config, SamPromptEncoderConfig): + prompt_encoder_config = prompt_encoder_config.to_dict() + if isinstance(mask_decoder_config, SamMaskDecoderConfig): + mask_decoder_config = mask_decoder_config.to_dict() + + self.vision_config = SamVisionConfig(**vision_config) + self.prompt_encoder_config = SamPromptEncoderConfig(**prompt_encoder_config) + self.mask_decoder_config = SamMaskDecoderConfig(**mask_decoder_config) + self.initializer_range = initializer_range + self.tie_word_embeddings = tie_word_embeddings + super().__init__(**kwargs) + + +__all__ = ["SamConfig", "SamMaskDecoderConfig", "SamPromptEncoderConfig", "SamVisionConfig"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam/image_processing_sam.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam/image_processing_sam.py new file mode 100644 index 0000000000000000000000000000000000000000..8d3fbf5b86bc7cba73dbba1935829a74ca2f8c8a --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam/image_processing_sam.py @@ -0,0 +1,1201 @@ +# Copyright 2023 The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""Image processor class for SAM.""" + +import math +from copy import deepcopy +from itertools import product +from typing import Any, Optional + +import numpy as np + +from ...image_processing_utils import BaseImageProcessor, BatchFeature, get_size_dict +from ...image_transforms import convert_to_rgb, pad, resize, to_channel_dimension_format +from ...image_utils import ( + IMAGENET_DEFAULT_MEAN, + IMAGENET_DEFAULT_STD, + ChannelDimension, + ImageInput, + PILImageResampling, + get_image_size, + infer_channel_dimension_format, + is_scaled_image, + make_flat_list_of_images, + to_numpy_array, + valid_images, + validate_preprocess_arguments, +) +from ...processing_utils import ImagesKwargs +from ...utils import ( + TensorType, + filter_out_non_signature_kwargs, + is_torch_available, + is_torchvision_available, + logging, + requires_backends, +) + + +if is_torch_available(): + import torch + import torch.nn.functional as F + +if is_torchvision_available(): + from torchvision.ops.boxes import batched_nms + +logger = logging.get_logger(__name__) + + +class SamImageProcessorKwargs(ImagesKwargs, total=False): + r""" + mask_size (`dict[str, int]`, *optional*): + The size `{"longest_edge": int}` to resize the segmentation maps to. + mask_pad_size (`dict[str, int]`, *optional*): + The size `{"height": int, "width": int}` to pad the segmentation maps to. Must be larger than any segmentation + map size provided for preprocessing. + """ + + mask_size: dict[str, int] + mask_pad_size: dict[str, int] + + +class SamImageProcessor(BaseImageProcessor): + r""" + Constructs a SAM image processor. + + Args: + do_resize (`bool`, *optional*, defaults to `True`): + Whether to resize the image's (height, width) dimensions to the specified `size`. Can be overridden by the + `do_resize` parameter in the `preprocess` method. + size (`dict`, *optional*, defaults to `{"longest_edge": 1024}`): + Size of the output image after resizing. Resizes the longest edge of the image to match + `size["longest_edge"]` while maintaining the aspect ratio. Can be overridden by the `size` parameter in the + `preprocess` method. + mask_size (`dict`, *optional*, defaults to `{"longest_edge": 256}`): + Size of the output segmentation map after resizing. Resizes the longest edge of the image to match + `size["longest_edge"]` while maintaining the aspect ratio. Can be overridden by the `mask_size` parameter + in the `preprocess` method. + resample (`PILImageResampling`, *optional*, defaults to `Resampling.BILINEAR`): + Resampling filter to use if resizing the image. Can be overridden by the `resample` parameter in the + `preprocess` method. + do_rescale (`bool`, *optional*, defaults to `True`): + Wwhether to rescale the image by the specified scale `rescale_factor`. Can be overridden by the + `do_rescale` parameter in the `preprocess` method. + rescale_factor (`int` or `float`, *optional*, defaults to `1/255`): + Scale factor to use if rescaling the image. Only has an effect if `do_rescale` is set to `True`. Can be + overridden by the `rescale_factor` parameter in the `preprocess` method. + do_normalize (`bool`, *optional*, defaults to `True`): + Whether to normalize the image. Can be overridden by the `do_normalize` parameter in the `preprocess` + method. Can be overridden by the `do_normalize` parameter in the `preprocess` method. + image_mean (`float` or `list[float]`, *optional*, defaults to `IMAGENET_DEFAULT_MEAN`): + Mean to use if normalizing the image. This is a float or list of floats the length of the number of + channels in the image. Can be overridden by the `image_mean` parameter in the `preprocess` method. Can be + overridden by the `image_mean` parameter in the `preprocess` method. + image_std (`float` or `list[float]`, *optional*, defaults to `IMAGENET_DEFAULT_STD`): + Standard deviation to use if normalizing the image. This is a float or list of floats the length of the + number of channels in the image. Can be overridden by the `image_std` parameter in the `preprocess` method. + Can be overridden by the `image_std` parameter in the `preprocess` method. + do_pad (`bool`, *optional*, defaults to `True`): + Whether to pad the image to the specified `pad_size`. Can be overridden by the `do_pad` parameter in the + `preprocess` method. + pad_size (`dict`, *optional*, defaults to `{"height": 1024, "width": 1024}`): + Size of the output image after padding. Can be overridden by the `pad_size` parameter in the `preprocess` + method. + mask_pad_size (`dict`, *optional*, defaults to `{"height": 256, "width": 256}`): + Size of the output segmentation map after padding. Can be overridden by the `mask_pad_size` parameter in + the `preprocess` method. + do_convert_rgb (`bool`, *optional*, defaults to `True`): + Whether to convert the image to RGB. + """ + + model_input_names = ["pixel_values"] + valid_kwargs = SamImageProcessorKwargs + + def __init__( + self, + do_resize: bool = True, + size: dict[str, int] | None = None, + mask_size: dict[str, int] | None = None, + resample: PILImageResampling = PILImageResampling.BILINEAR, + do_rescale: bool = True, + rescale_factor: int | float = 1 / 255, + do_normalize: bool = True, + image_mean: float | list[float] | None = None, + image_std: float | list[float] | None = None, + do_pad: bool = True, + pad_size: int | None = None, + mask_pad_size: int | None = None, + do_convert_rgb: bool = True, + **kwargs, + ) -> None: + super().__init__(**kwargs) + size = size if size is not None else {"longest_edge": 1024} + size = get_size_dict(max_size=size, default_to_square=False) if not isinstance(size, dict) else size + + pad_size = pad_size if pad_size is not None else {"height": 1024, "width": 1024} + pad_size = get_size_dict(pad_size, default_to_square=True) + + mask_size = mask_size if mask_size is not None else {"longest_edge": 256} + mask_size = ( + get_size_dict(max_size=mask_size, default_to_square=False) + if not isinstance(mask_size, dict) + else mask_size + ) + + mask_pad_size = mask_pad_size if mask_pad_size is not None else {"height": 256, "width": 256} + mask_pad_size = get_size_dict(mask_pad_size, default_to_square=True) + + self.do_resize = do_resize + self.size = size + self.mask_size = mask_size + self.resample = resample + self.do_rescale = do_rescale + self.rescale_factor = rescale_factor + self.do_normalize = do_normalize + self.image_mean = image_mean if image_mean is not None else IMAGENET_DEFAULT_MEAN + self.image_std = image_std if image_std is not None else IMAGENET_DEFAULT_STD + self.do_pad = do_pad + self.pad_size = pad_size + self.mask_pad_size = mask_pad_size + self.do_convert_rgb = do_convert_rgb + + def pad_image( + self, + image: np.ndarray, + pad_size: dict[str, int], + data_format: str | ChannelDimension | None = None, + input_data_format: str | ChannelDimension | None = None, + **kwargs, + ) -> np.ndarray: + """ + Pad an image to `(pad_size["height"], pad_size["width"])` with zeros to the right and bottom. + + Args: + image (`np.ndarray`): + Image to pad. + pad_size (`dict[str, int]`): + Size of the output image after padding. + data_format (`str` or `ChannelDimension`, *optional*): + The data format of the image. Can be either "channels_first" or "channels_last". If `None`, the + `data_format` of the `image` will be used. + input_data_format (`str` or `ChannelDimension`, *optional*): + The channel dimension format of the input image. If not provided, it will be inferred. + """ + output_height, output_width = pad_size["height"], pad_size["width"] + input_height, input_width = get_image_size(image, channel_dim=input_data_format) + + pad_width = output_width - input_width + pad_height = output_height - input_height + + padded_image = pad( + image, + ((0, pad_height), (0, pad_width)), + data_format=data_format, + input_data_format=input_data_format, + **kwargs, + ) + return padded_image + + def _get_preprocess_shape(self, old_shape: tuple[int, int], longest_edge: int): + """ + Compute the output size given input size and target long side length. + """ + oldh, oldw = old_shape + scale = longest_edge * 1.0 / max(oldh, oldw) + newh, neww = oldh * scale, oldw * scale + newh = int(newh + 0.5) + neww = int(neww + 0.5) + return (newh, neww) + + def resize( + self, + image: np.ndarray, + size: dict[str, int], + resample: PILImageResampling = PILImageResampling.BICUBIC, + data_format: str | ChannelDimension | None = None, + input_data_format: str | ChannelDimension | None = None, + **kwargs, + ) -> np.ndarray: + """ + Resize an image to `(size["height"], size["width"])`. + + Args: + image (`np.ndarray`): + Image to resize. + size (`dict[str, int]`): + Dictionary in the format `{"longest_edge": int}` specifying the size of the output image. The longest + edge of the image will be resized to the specified size, while the other edge will be resized to + maintain the aspect ratio. + resample: + `PILImageResampling` filter to use when resizing the image e.g. `PILImageResampling.BILINEAR`. + data_format (`ChannelDimension` or `str`, *optional*): + The channel dimension format for the output image. If unset, the channel dimension format of the input + image is used. Can be one of: + - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format. + - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format. + input_data_format (`ChannelDimension` or `str`, *optional*): + The channel dimension format for the input image. If unset, the channel dimension format is inferred + from the input image. Can be one of: + - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format. + - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format. + + Returns: + `np.ndarray`: The resized image. + """ + size = get_size_dict(size) + if "longest_edge" not in size: + raise ValueError(f"The `size` dictionary must contain the key `longest_edge`. Got {size.keys()}") + input_size = get_image_size(image, channel_dim=input_data_format) + output_height, output_width = self._get_preprocess_shape(input_size, size["longest_edge"]) + return resize( + image, + size=(output_height, output_width), + resample=resample, + data_format=data_format, + input_data_format=input_data_format, + **kwargs, + ) + + def _preprocess( + self, + image: ImageInput, + do_resize: bool, + do_rescale: bool, + do_normalize: bool, + size: dict[str, int] | None = None, + resample: PILImageResampling | None = None, + rescale_factor: float | None = None, + image_mean: float | list[float] | None = None, + image_std: float | list[float] | None = None, + do_pad: bool | None = None, + pad_size: dict[str, int] | None = None, + input_data_format: str | ChannelDimension | None = None, + ): + if do_resize: + image = self.resize(image=image, size=size, resample=resample, input_data_format=input_data_format) + reshaped_input_size = get_image_size(image, channel_dim=input_data_format) + + if do_rescale: + image = self.rescale(image=image, scale=rescale_factor, input_data_format=input_data_format) + + if do_normalize: + image = self.normalize(image=image, mean=image_mean, std=image_std, input_data_format=input_data_format) + + if do_pad: + image = self.pad_image(image=image, pad_size=pad_size, input_data_format=input_data_format) + + return image, reshaped_input_size + + def _preprocess_image( + self, + image: ImageInput, + do_resize: bool | None = None, + size: dict[str, int] | None = None, + resample: PILImageResampling | None = None, + do_rescale: bool | None = None, + rescale_factor: float | None = None, + do_normalize: bool | None = None, + image_mean: float | list[float] | None = None, + image_std: float | list[float] | None = None, + do_pad: bool | None = None, + pad_size: dict[str, int] | None = None, + do_convert_rgb: bool | None = None, + data_format: str | ChannelDimension | None = None, + input_data_format: str | ChannelDimension | None = None, + ) -> tuple[np.ndarray, tuple[int, int], tuple[int, int]]: + # PIL RGBA images are converted to RGB + if do_convert_rgb: + image = convert_to_rgb(image) + + # All transformations expect numpy arrays. + image = to_numpy_array(image) + + if do_rescale and is_scaled_image(image): + logger.warning_once( + "It looks like you are trying to rescale already rescaled images. If the input" + " images have pixel values between 0 and 1, set `do_rescale=False` to avoid rescaling them again." + ) + + if input_data_format is None: + input_data_format = infer_channel_dimension_format(image) + + original_size = get_image_size(image, channel_dim=input_data_format) + + image, reshaped_input_size = self._preprocess( + image=image, + do_resize=do_resize, + size=size, + resample=resample, + do_rescale=do_rescale, + rescale_factor=rescale_factor, + do_normalize=do_normalize, + image_mean=image_mean, + image_std=image_std, + do_pad=do_pad, + pad_size=pad_size, + input_data_format=input_data_format, + ) + + if data_format is not None: + image = to_channel_dimension_format(image, data_format, input_channel_dim=input_data_format) + + return image, original_size, reshaped_input_size + + def _preprocess_mask( + self, + segmentation_map: ImageInput, + do_resize: bool | None = None, + mask_size: dict[str, int] | None = None, + do_pad: bool | None = None, + mask_pad_size: dict[str, int] | None = None, + input_data_format: str | ChannelDimension | None = None, + ) -> np.ndarray: + segmentation_map = to_numpy_array(segmentation_map) + + # Add channel dimension if missing - needed for certain transformations + if segmentation_map.ndim == 2: + added_channel_dim = True + segmentation_map = segmentation_map[None, ...] + input_data_format = ChannelDimension.FIRST + else: + added_channel_dim = False + if input_data_format is None: + input_data_format = infer_channel_dimension_format(segmentation_map, num_channels=1) + + original_size = get_image_size(segmentation_map, channel_dim=input_data_format) + + segmentation_map, _ = self._preprocess( + image=segmentation_map, + do_resize=do_resize, + size=mask_size, + resample=PILImageResampling.NEAREST, + do_rescale=False, + do_normalize=False, + do_pad=do_pad, + pad_size=mask_pad_size, + input_data_format=input_data_format, + ) + + # Remove extra channel dimension if added for processing + if added_channel_dim: + segmentation_map = segmentation_map.squeeze(0) + segmentation_map = segmentation_map.astype(np.int64) + + return segmentation_map, original_size + + def __call__(self, images, segmentation_maps=None, **kwargs): + # Overrides the `__call__` method of the `BaseImageProcessor` class such that the images and segmentation maps can both + # be passed in as positional arguments. + return super().__call__(images, segmentation_maps=segmentation_maps, **kwargs) + + @filter_out_non_signature_kwargs() + def preprocess( + self, + images: ImageInput, + segmentation_maps: ImageInput | None = None, + do_resize: bool | None = None, + size: dict[str, int] | None = None, + mask_size: dict[str, int] | None = None, + resample: Optional["PILImageResampling"] = None, + do_rescale: bool | None = None, + rescale_factor: int | float | None = None, + do_normalize: bool | None = None, + image_mean: float | list[float] | None = None, + image_std: float | list[float] | None = None, + do_pad: bool | None = None, + pad_size: dict[str, int] | None = None, + mask_pad_size: dict[str, int] | None = None, + do_convert_rgb: bool | None = None, + return_tensors: str | TensorType | None = None, + data_format: ChannelDimension = ChannelDimension.FIRST, + input_data_format: str | ChannelDimension | None = None, + ): + """ + Preprocess an image or batch of images. + + Args: + images (`ImageInput`): + Image to preprocess. Expects a single or batch of images with pixel values ranging from 0 to 255. If + passing in images with pixel values between 0 and 1, set `do_rescale=False`. + segmentation_maps (`ImageInput`, *optional*): + Segmentation map to preprocess. + do_resize (`bool`, *optional*, defaults to `self.do_resize`): + Whether to resize the image. + size (`dict[str, int]`, *optional*, defaults to `self.size`): + Controls the size of the image after `resize`. The longest edge of the image is resized to + `size["longest_edge"]` whilst preserving the aspect ratio. + mask_size (`dict[str, int]`, *optional*, defaults to `self.mask_size`): + Controls the size of the segmentation map after `resize`. The longest edge of the image is resized to + `size["longest_edge"]` whilst preserving the aspect ratio. + resample (`PILImageResampling`, *optional*, defaults to `self.resample`): + `PILImageResampling` filter to use when resizing the image e.g. `PILImageResampling.BILINEAR`. + do_rescale (`bool`, *optional*, defaults to `self.do_rescale`): + Whether to rescale the image pixel values by rescaling factor. + rescale_factor (`int` or `float`, *optional*, defaults to `self.rescale_factor`): + Rescale factor to apply to the image pixel values. + do_normalize (`bool`, *optional*, defaults to `self.do_normalize`): + Whether to normalize the image. + image_mean (`float` or `list[float]`, *optional*, defaults to `self.image_mean`): + Image mean to normalize the image by if `do_normalize` is set to `True`. + image_std (`float` or `list[float]`, *optional*, defaults to `self.image_std`): + Image standard deviation to normalize the image by if `do_normalize` is set to `True`. + do_pad (`bool`, *optional*, defaults to `self.do_pad`): + Whether to pad the image. + pad_size (`dict[str, int]`, *optional*, defaults to `self.pad_size`): + Controls the size of the padding applied to the image. The image is padded to `pad_size["height"]` and + `pad_size["width"]` if `do_pad` is set to `True`. + mask_pad_size (`dict[str, int]`, *optional*, defaults to `self.mask_pad_size`): + Controls the size of the padding applied to the segmentation map. The image is padded to + `mask_pad_size["height"]` and `mask_pad_size["width"]` if `do_pad` is set to `True`. + do_convert_rgb (`bool`, *optional*, defaults to `self.do_convert_rgb`): + Whether to convert the image to RGB. + return_tensors (`str` or `TensorType`, *optional*): + The type of tensors to return. Can be one of: + - Unset: Return a list of `np.ndarray`. + - `TensorType.PYTORCH` or `'pt'`: Return a batch of type `torch.Tensor`. + - `TensorType.NUMPY` or `'np'`: Return a batch of type `np.ndarray`. + data_format (`ChannelDimension` or `str`, *optional*, defaults to `ChannelDimension.FIRST`): + The channel dimension format for the output image. Can be one of: + - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format. + - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format. + - Unset: Use the channel dimension format of the input image. + input_data_format (`ChannelDimension` or `str`, *optional*): + The channel dimension format for the input image. If unset, the channel dimension format is inferred + from the input image. Can be one of: + - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format. + - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format. + - `"none"` or `ChannelDimension.NONE`: image in (height, width) format. + """ + do_resize = do_resize if do_resize is not None else self.do_resize + size = size if size is not None else self.size + size = get_size_dict(max_size=size, default_to_square=False) if not isinstance(size, dict) else size + mask_size = mask_size if mask_size is not None else self.mask_size + mask_size = ( + get_size_dict(max_size=mask_size, default_to_square=False) + if not isinstance(mask_size, dict) + else mask_size + ) + resample = resample if resample is not None else self.resample + do_rescale = do_rescale if do_rescale is not None else self.do_rescale + rescale_factor = rescale_factor if rescale_factor is not None else self.rescale_factor + do_normalize = do_normalize if do_normalize is not None else self.do_normalize + image_mean = image_mean if image_mean is not None else self.image_mean + image_std = image_std if image_std is not None else self.image_std + do_pad = do_pad if do_pad is not None else self.do_pad + pad_size = pad_size if pad_size is not None else self.pad_size + pad_size = get_size_dict(pad_size, default_to_square=True) + mask_pad_size = mask_pad_size if mask_pad_size is not None else self.mask_pad_size + mask_pad_size = get_size_dict(mask_pad_size, default_to_square=True) + do_convert_rgb = do_convert_rgb if do_convert_rgb is not None else self.do_convert_rgb + + images = make_flat_list_of_images(images) + + if not valid_images(images): + raise ValueError("Invalid image type. Must be of type PIL.Image.Image, numpy.ndarray, or torch.Tensor.") + + if segmentation_maps is not None: + segmentation_maps = make_flat_list_of_images(segmentation_maps, expected_ndims=2) + + if not valid_images(segmentation_maps): + raise ValueError( + "Invalid segmentation map type. Must be of type PIL.Image.Image, numpy.ndarray, or torch.Tensor." + ) + validate_preprocess_arguments( + do_rescale=do_rescale, + rescale_factor=rescale_factor, + do_normalize=do_normalize, + image_mean=image_mean, + image_std=image_std, + do_resize=do_resize, + size=size, + resample=resample, + ) + + images, original_sizes, reshaped_input_sizes = zip( + *( + self._preprocess_image( + image=img, + do_resize=do_resize, + size=size, + resample=resample, + do_rescale=do_rescale, + rescale_factor=rescale_factor, + do_normalize=do_normalize, + image_mean=image_mean, + image_std=image_std, + do_pad=do_pad, + pad_size=pad_size, + do_convert_rgb=do_convert_rgb, + data_format=data_format, + input_data_format=input_data_format, + ) + for img in images + ) + ) + + data = { + "pixel_values": images, + "original_sizes": original_sizes, + "reshaped_input_sizes": reshaped_input_sizes, + } + + if segmentation_maps is not None: + segmentation_maps, original_mask_sizes = zip( + *( + self._preprocess_mask( + segmentation_map=mask, + do_resize=do_resize, + mask_size=mask_size, + do_pad=do_pad, + mask_pad_size=mask_pad_size, + input_data_format=input_data_format, + ) + for mask in segmentation_maps + ) + ) + + # masks should start out the same size as input images + assert all( + original_im_size == original_mask_size + for original_im_size, original_mask_size in zip(original_sizes, original_mask_sizes) + ), "Segmentation maps should be the same size as input images." + + data["labels"] = segmentation_maps + + return BatchFeature(data=data, tensor_type=return_tensors) + + def post_process_masks( + self, + masks, + original_sizes, + reshaped_input_sizes, + mask_threshold=0.0, + binarize=True, + pad_size=None, + return_tensors="pt", + ): + """ + Remove padding and upscale masks to the original image size. + + Args: + masks (`Union[list[torch.Tensor], list[np.ndarray]]`): + Batched masks from the mask_decoder in (batch_size, num_channels, height, width) format. + original_sizes (`Union[torch.Tensor, list[tuple[int,int]]]`): + The original sizes of each image before it was resized to the model's expected input shape, in (height, + width) format. + reshaped_input_sizes (`Union[torch.Tensor, list[tuple[int,int]]]`): + The size of each image as it is fed to the model, in (height, width) format. Used to remove padding. + mask_threshold (`float`, *optional*, defaults to 0.0): + The threshold to use for binarizing the masks. + binarize (`bool`, *optional*, defaults to `True`): + Whether to binarize the masks. + pad_size (`int`, *optional*, defaults to `self.pad_size`): + The target size the images were padded to before being passed to the model. If None, the target size is + assumed to be the processor's `pad_size`. + return_tensors (`str`, *optional*, defaults to `"pt"`): + If `"pt"`, return PyTorch tensors. + Returns: + (`torch.Tensor`): Batched masks in batch_size, num_channels, height, width) format, where + (height, width) is given by original_size. + """ + if return_tensors == "pt": + return self._post_process_masks_pt( + masks=masks, + original_sizes=original_sizes, + reshaped_input_sizes=reshaped_input_sizes, + mask_threshold=mask_threshold, + binarize=binarize, + pad_size=pad_size, + ) + else: + raise ValueError("return_tensors must be 'pt'") + + def _post_process_masks_pt( + self, masks, original_sizes, reshaped_input_sizes, mask_threshold=0.0, binarize=True, pad_size=None + ): + """ + Remove padding and upscale masks to the original image size. + + Args: + masks (`Union[list[torch.Tensor], list[np.ndarray]]`): + Batched masks from the mask_decoder in (batch_size, num_channels, height, width) format. + original_sizes (`Union[torch.Tensor, list[tuple[int,int]]]`): + The original sizes of each image before it was resized to the model's expected input shape, in (height, + width) format. + reshaped_input_sizes (`Union[torch.Tensor, list[tuple[int,int]]]`): + The size of each image as it is fed to the model, in (height, width) format. Used to remove padding. + mask_threshold (`float`, *optional*, defaults to 0.0): + The threshold to use for binarizing the masks. + binarize (`bool`, *optional*, defaults to `True`): + Whether to binarize the masks. + pad_size (`int`, *optional*, defaults to `self.pad_size`): + The target size the images were padded to before being passed to the model. If None, the target size is + assumed to be the processor's `pad_size`. + Returns: + (`torch.Tensor`): Batched masks in batch_size, num_channels, height, width) format, where (height, width) + is given by original_size. + """ + requires_backends(self, ["torch"]) + pad_size = self.pad_size if pad_size is None else pad_size + target_image_size = (pad_size["height"], pad_size["width"]) + if isinstance(original_sizes, (torch.Tensor, np.ndarray)): + original_sizes = original_sizes.tolist() + if isinstance(reshaped_input_sizes, (torch.Tensor, np.ndarray)): + reshaped_input_sizes = reshaped_input_sizes.tolist() + output_masks = [] + for i, original_size in enumerate(original_sizes): + if isinstance(masks[i], np.ndarray): + masks[i] = torch.from_numpy(masks[i]) + elif not isinstance(masks[i], torch.Tensor): + raise TypeError("Input masks should be a list of `torch.tensors` or a list of `np.ndarray`") + interpolated_mask = F.interpolate(masks[i], target_image_size, mode="bilinear", align_corners=False) + interpolated_mask = interpolated_mask[..., : reshaped_input_sizes[i][0], : reshaped_input_sizes[i][1]] + interpolated_mask = F.interpolate(interpolated_mask, original_size, mode="bilinear", align_corners=False) + if binarize: + interpolated_mask = interpolated_mask > mask_threshold + output_masks.append(interpolated_mask) + + return output_masks + + def post_process_for_mask_generation( + self, all_masks, all_scores, all_boxes, crops_nms_thresh, return_tensors="pt" + ): + """ + Post processes mask that are generated by calling the Non Maximum Suppression algorithm on the predicted masks. + + Args: + all_masks (`list[torch.Tensor]`): + List of all predicted segmentation masks + all_scores (`list[torch.Tensor]`): + List of all predicted iou scores + all_boxes (`list[torch.Tensor]`): + List of all bounding boxes of the predicted masks + crops_nms_thresh (`float`): + Threshold for NMS (Non Maximum Suppression) algorithm. + return_tensors (`str`, *optional*, defaults to `pt`): + If `pt`, returns `torch.Tensor`. + """ + if return_tensors == "pt": + return _postprocess_for_mg(all_masks, all_scores, all_boxes, crops_nms_thresh) + + def generate_crop_boxes( + self, + image, + target_size, + crop_n_layers: int = 0, + overlap_ratio: float = 512 / 1500, + points_per_crop: int | None = 32, + crop_n_points_downscale_factor: list[int] | None = 1, + device: Optional["torch.device"] = None, + input_data_format: str | ChannelDimension | None = None, + return_tensors: str = "pt", + ): + """ + Generates a list of crop boxes of different sizes. Each layer has (2**i)**2 boxes for the ith layer. + + Args: + image (`np.ndarray`): + Input original image + target_size (`int`): + Target size of the resized image + crop_n_layers (`int`, *optional*, defaults to 0): + If >0, mask prediction will be run again on crops of the image. Sets the number of layers to run, where + each layer has 2**i_layer number of image crops. + overlap_ratio (`float`, *optional*, defaults to 512/1500): + Sets the degree to which crops overlap. In the first crop layer, crops will overlap by this fraction of + the image length. Later layers with more crops scale down this overlap. + points_per_crop (`int`, *optional*, defaults to 32): + Number of points to sample from each crop. + crop_n_points_downscale_factor (`list[int]`, *optional*, defaults to 1): + The number of points-per-side sampled in layer n is scaled down by crop_n_points_downscale_factor**n. + device (`torch.device`, *optional*, defaults to None): + Device to use for the computation. If None, cpu will be used. + input_data_format (`str` or `ChannelDimension`, *optional*): + The channel dimension format of the input image. If not provided, it will be inferred. + return_tensors (`str`, *optional*, defaults to `pt`): + If `pt`, returns `torch.Tensor`. + """ + crop_boxes, points_per_crop, cropped_images, input_labels = _generate_crop_boxes( + image, + target_size, + crop_n_layers, + overlap_ratio, + points_per_crop, + crop_n_points_downscale_factor, + input_data_format, + ) + if return_tensors == "pt": + if device is None: + device = torch.device("cpu") + crop_boxes = torch.tensor(crop_boxes, device=device) + points_per_crop = torch.tensor(points_per_crop, device=device) + # cropped_images stays as np + input_labels = torch.tensor(input_labels, device=device) + + else: + raise ValueError("return_tensors must be either `'pt'` or `None`") + return crop_boxes, points_per_crop, cropped_images, input_labels + + def filter_masks( + self, + masks, + iou_scores, + original_size, + cropped_box_image, + pred_iou_thresh=0.88, + stability_score_thresh=0.95, + mask_threshold=0, + stability_score_offset=1, + return_tensors="pt", + ): + """ + Filters the predicted masks by selecting only the ones that meets several criteria. The first criterion being + that the iou scores needs to be greater than `pred_iou_thresh`. The second criterion is that the stability + score needs to be greater than `stability_score_thresh`. The method also converts the predicted masks to + bounding boxes and pad the predicted masks if necessary. + + Args: + masks (`torch.Tensor`): + Input masks. + iou_scores (`torch.Tensor`): + List of IoU scores. + original_size (`tuple[int,int]`): + Size of the original image. + cropped_box_image (`np.ndarray`): + The cropped image. + pred_iou_thresh (`float`, *optional*, defaults to 0.88): + The threshold for the iou scores. + stability_score_thresh (`float`, *optional*, defaults to 0.95): + The threshold for the stability score. + mask_threshold (`float`, *optional*, defaults to 0): + The threshold for the predicted masks. + stability_score_offset (`float`, *optional*, defaults to 1): + The offset for the stability score used in the `_compute_stability_score` method. + return_tensors (`str`, *optional*, defaults to `pt`): + If `pt`, returns `torch.Tensor`. + """ + if return_tensors == "pt": + return self._filter_masks_pt( + masks=masks, + iou_scores=iou_scores, + original_size=original_size, + cropped_box_image=cropped_box_image, + pred_iou_thresh=pred_iou_thresh, + stability_score_thresh=stability_score_thresh, + mask_threshold=mask_threshold, + stability_score_offset=stability_score_offset, + ) + + def _filter_masks_pt( + self, + masks, + iou_scores, + original_size, + cropped_box_image, + pred_iou_thresh=0.88, + stability_score_thresh=0.95, + mask_threshold=0, + stability_score_offset=1, + ): + """ + Filters the predicted masks by selecting only the ones that meets several criteria. The first criterion being + that the iou scores needs to be greater than `pred_iou_thresh`. The second criterion is that the stability + score needs to be greater than `stability_score_thresh`. The method also converts the predicted masks to + bounding boxes and pad the predicted masks if necessary. + + Args: + masks (`torch.Tensor`): + Input masks. + iou_scores (`torch.Tensor`): + List of IoU scores. + original_size (`tuple[int,int]`): + Size of the original image. + cropped_box_image (`np.ndarray`): + The cropped image. + pred_iou_thresh (`float`, *optional*, defaults to 0.88): + The threshold for the iou scores. + stability_score_thresh (`float`, *optional*, defaults to 0.95): + The threshold for the stability score. + mask_threshold (`float`, *optional*, defaults to 0): + The threshold for the predicted masks. + stability_score_offset (`float`, *optional*, defaults to 1): + The offset for the stability score used in the `_compute_stability_score` method. + + """ + requires_backends(self, ["torch"]) + original_height, original_width = original_size + iou_scores = iou_scores.flatten(0, 1) + masks = masks.flatten(0, 1) + + if masks.shape[0] != iou_scores.shape[0]: + raise ValueError("masks and iou_scores must have the same batch size.") + + if masks.device != iou_scores.device: + iou_scores = iou_scores.to(masks.device) + + batch_size = masks.shape[0] + + keep_mask = torch.ones(batch_size, dtype=torch.bool, device=masks.device) + + if pred_iou_thresh > 0.0: + keep_mask = keep_mask & (iou_scores > pred_iou_thresh) + + # compute stability score + if stability_score_thresh > 0.0: + stability_scores = _compute_stability_score_pt(masks, mask_threshold, stability_score_offset) + keep_mask = keep_mask & (stability_scores > stability_score_thresh) + + scores = iou_scores[keep_mask] + masks = masks[keep_mask] + + # binarize masks + masks = masks > mask_threshold + converted_boxes = _batched_mask_to_box(masks) + + keep_mask = ~_is_box_near_crop_edge( + converted_boxes, cropped_box_image, [0, 0, original_width, original_height] + ) + + scores = scores[keep_mask] + masks = masks[keep_mask] + converted_boxes = converted_boxes[keep_mask] + + masks = _pad_masks(masks, cropped_box_image, original_height, original_width) + # conversion to rle is necessary to run non-maximum suppression + masks = _mask_to_rle_pytorch(masks) + + return masks, scores, converted_boxes + + +def _compute_stability_score_pt(masks: "torch.Tensor", mask_threshold: float, stability_score_offset: int): + # One mask is always contained inside the other. + # Save memory by preventing unnecessary cast to torch.int64 + intersections = ( + (masks > (mask_threshold + stability_score_offset)).sum(-1, dtype=torch.int16).sum(-1, dtype=torch.int32) + ) + unions = (masks > (mask_threshold - stability_score_offset)).sum(-1, dtype=torch.int16).sum(-1, dtype=torch.int32) + stability_scores = intersections / unions + return stability_scores + + +def _build_point_grid(n_per_side: int) -> np.ndarray: + """Generates a 2D grid of points evenly spaced in [0,1]x[0,1].""" + offset = 1 / (2 * n_per_side) + points_one_side = np.linspace(offset, 1 - offset, n_per_side) + points_x = np.tile(points_one_side[None, :], (n_per_side, 1)) + points_y = np.tile(points_one_side[:, None], (1, n_per_side)) + points = np.stack([points_x, points_y], axis=-1).reshape(-1, 2) + return points + + +def _normalize_coordinates( + target_size: int, coords: np.ndarray, original_size: tuple[int, int], is_bounding_box=False +) -> np.ndarray: + """ + Expects a numpy array of length 2 in the final dimension. Requires the original image size in (height, width) + format. + """ + old_height, old_width = original_size + + scale = target_size * 1.0 / max(old_height, old_width) + new_height, new_width = old_height * scale, old_width * scale + new_width = int(new_width + 0.5) + new_height = int(new_height + 0.5) + + coords = deepcopy(coords).astype(float) + + if is_bounding_box: + coords = coords.reshape(-1, 2, 2) + + coords[..., 0] = coords[..., 0] * (new_width / old_width) + coords[..., 1] = coords[..., 1] * (new_height / old_height) + + if is_bounding_box: + coords = coords.reshape(-1, 4) + + return coords + + +def _generate_crop_boxes( + image, + target_size: int, # Is it tuple here? + crop_n_layers: int = 0, + overlap_ratio: float = 512 / 1500, + points_per_crop: int | None = 32, + crop_n_points_downscale_factor: list[int] | None = 1, + input_data_format: str | ChannelDimension | None = None, +) -> tuple[list[list[int]], list[int]]: + """ + Generates a list of crop boxes of different sizes. Each layer has (2**i)**2 boxes for the ith layer. + + Args: + image (Union[`numpy.ndarray`, `PIL.Image`, `torch.Tensor`]): + Image to generate crops for. + target_size (`int`): + Size of the smallest crop. + crop_n_layers (`int`, *optional*): + If `crops_n_layers>0`, mask prediction will be run again on crops of the image. Sets the number of layers + to run, where each layer has 2**i_layer number of image crops. + overlap_ratio (`int`, *optional*): + Sets the degree to which crops overlap. In the first crop layer, crops will overlap by this fraction of the + image length. Later layers with more crops scale down this overlap. + points_per_crop (`int`, *optional*): + Number of points to sample per crop. + crop_n_points_downscale_factor (`int`, *optional*): + The number of points-per-side sampled in layer n is scaled down by crop_n_points_downscale_factor**n. + input_data_format (`str` or `ChannelDimension`, *optional*): + The channel dimension format of the input image. If not provided, it will be inferred. + """ + + if isinstance(image, list): + raise TypeError("Only one image is allowed for crop generation.") + image = to_numpy_array(image) + original_size = get_image_size(image, input_data_format) + + points_grid = [] + for i in range(crop_n_layers + 1): + n_points = int(points_per_crop / (crop_n_points_downscale_factor**i)) + points_grid.append(_build_point_grid(n_points)) + + crop_boxes, layer_idxs = _generate_per_layer_crops(crop_n_layers, overlap_ratio, original_size) + + cropped_images, point_grid_per_crop = _generate_crop_images( + crop_boxes, image, points_grid, layer_idxs, target_size, original_size, input_data_format + ) + crop_boxes = np.array(crop_boxes) + crop_boxes = crop_boxes.astype(np.float32) + points_per_crop = np.array([point_grid_per_crop]) + points_per_crop = np.transpose(points_per_crop, axes=(0, 2, 1, 3)) + + input_labels = np.ones_like(points_per_crop[:, :, :, 0], dtype=np.int64) + + return crop_boxes, points_per_crop, cropped_images, input_labels + + +def _generate_per_layer_crops(crop_n_layers, overlap_ratio, original_size): + """ + Generates 2 ** (layers idx + 1) crops for each crop_n_layers. Crops are in the XYWH format : The XYWH format + consists of the following required indices: + - X: X coordinate of the top left of the bounding box + - Y: Y coordinate of the top left of the bounding box + - W: width of the bounding box + - H: height of the bounding box + """ + crop_boxes, layer_idxs = [], [] + im_height, im_width = original_size + short_side = min(im_height, im_width) + + # Original image + crop_boxes.append([0, 0, im_width, im_height]) + layer_idxs.append(0) + for i_layer in range(crop_n_layers): + n_crops_per_side = 2 ** (i_layer + 1) + overlap = int(overlap_ratio * short_side * (2 / n_crops_per_side)) + + crop_width = int(math.ceil((overlap * (n_crops_per_side - 1) + im_width) / n_crops_per_side)) + crop_height = int(math.ceil((overlap * (n_crops_per_side - 1) + im_height) / n_crops_per_side)) + + crop_box_x0 = [int((crop_width - overlap) * i) for i in range(n_crops_per_side)] + crop_box_y0 = [int((crop_height - overlap) * i) for i in range(n_crops_per_side)] + + for left, top in product(crop_box_x0, crop_box_y0): + box = [left, top, min(left + crop_width, im_width), min(top + crop_height, im_height)] + crop_boxes.append(box) + layer_idxs.append(i_layer + 1) + + return crop_boxes, layer_idxs + + +def _generate_crop_images( + crop_boxes, image, points_grid, layer_idxs, target_size, original_size, input_data_format=None +): + """ + Takes as an input bounding boxes that are used to crop the image. Based in the crops, the corresponding points are + also passed. + """ + cropped_images = [] + total_points_per_crop = [] + for i, crop_box in enumerate(crop_boxes): + left, top, right, bottom = crop_box + + channel_dim = infer_channel_dimension_format(image, input_data_format) + if channel_dim == ChannelDimension.LAST: + cropped_im = image[top:bottom, left:right, :] + else: + cropped_im = image[:, top:bottom, left:right] + + cropped_images.append(cropped_im) + + cropped_im_size = get_image_size(cropped_im, channel_dim) + points_scale = np.array(cropped_im_size)[None, ::-1] + + points = points_grid[layer_idxs[i]] * points_scale + normalized_points = _normalize_coordinates(target_size, points, original_size) + total_points_per_crop.append(normalized_points) + + return cropped_images, total_points_per_crop + + +def _pad_masks(masks, crop_box: list[int], orig_height: int, orig_width: int): + left, top, right, bottom = crop_box + if left == 0 and top == 0 and right == orig_width and bottom == orig_height: + return masks + # Coordinate transform masks + pad_x, pad_y = orig_width - (right - left), orig_height - (bottom - top) + pad = (left, pad_x - left, top, pad_y - top) + return torch.nn.functional.pad(masks, pad, value=0) + + +def _is_box_near_crop_edge(boxes, crop_box, orig_box, atol=20.0): + """Filter masks at the edge of a crop, but not at the edge of the original image.""" + crop_box_torch = torch.as_tensor(crop_box, dtype=torch.float, device=boxes.device) + orig_box_torch = torch.as_tensor(orig_box, dtype=torch.float, device=boxes.device) + + left, top, _, _ = crop_box + offset = torch.tensor([[left, top, left, top]], device=boxes.device) + # Check if boxes has a channel dimension + if len(boxes.shape) == 3: + offset = offset.unsqueeze(1) + boxes = (boxes + offset).float() + + near_crop_edge = torch.isclose(boxes, crop_box_torch[None, :], atol=atol, rtol=0) + near_image_edge = torch.isclose(boxes, orig_box_torch[None, :], atol=atol, rtol=0) + near_crop_edge = torch.logical_and(near_crop_edge, ~near_image_edge) + return torch.any(near_crop_edge, dim=1) + + +def _batched_mask_to_box(masks: "torch.Tensor"): + """ + Computes the bounding boxes around the given input masks. The bounding boxes are in the XYXY format which + corresponds the following required indices: + - LEFT: left hand side of the bounding box + - TOP: top of the bounding box + - RIGHT: right of the bounding box + - BOTTOM: bottom of the bounding box + + Return [0,0,0,0] for an empty mask. For input shape channel_1 x channel_2 x ... x height x width, the output shape + is channel_1 x channel_2 x ... x 4. + + Args: + - masks (`torch.Tensor` of shape `(batch, nb_mask, height, width)`) + """ + # torch.max below raises an error on empty inputs, just skip in this case + + if torch.numel(masks) == 0: + return torch.zeros(*masks.shape[:-2], 4, device=masks.device) + + # Normalize shape to Cxheightxwidth + shape = masks.shape + height, width = shape[-2:] + + # Get top and bottom edges + in_height, _ = torch.max(masks, dim=-1) + in_height_coords = in_height * torch.arange(height, device=in_height.device)[None, :] + bottom_edges, _ = torch.max(in_height_coords, dim=-1) + in_height_coords = in_height_coords + height * (~in_height) + top_edges, _ = torch.min(in_height_coords, dim=-1) + + # Get left and right edges + in_width, _ = torch.max(masks, dim=-2) + in_width_coords = in_width * torch.arange(width, device=in_width.device)[None, :] + right_edges, _ = torch.max(in_width_coords, dim=-1) + in_width_coords = in_width_coords + width * (~in_width) + left_edges, _ = torch.min(in_width_coords, dim=-1) + + # If the mask is empty the right edge will be to the left of the left edge. + # Replace these boxes with [0, 0, 0, 0] + empty_filter = (right_edges < left_edges) | (bottom_edges < top_edges) + out = torch.stack([left_edges, top_edges, right_edges, bottom_edges], dim=-1) + out = out * (~empty_filter).unsqueeze(-1) + + # Return to original shape + out = out.reshape(*shape[:-2], 4) + return out + + +def _mask_to_rle_pytorch(input_mask: "torch.Tensor"): + """ + Encodes masks the run-length encoding (RLE), in the format expected by pycoco tools. + """ + # Put in fortran order and flatten height and width + batch_size, height, width = input_mask.shape + input_mask = input_mask.permute(0, 2, 1).flatten(1) + + # Compute change indices + diff = input_mask[:, 1:] ^ input_mask[:, :-1] + change_indices = diff.nonzero() + + # Encode run length + out = [] + for i in range(batch_size): + cur_idxs = change_indices[change_indices[:, 0] == i, 1] + 1 + if len(cur_idxs) == 0: + # No changes => either all 0 or all 1 + # If the entire mask is 0, RLE is [height*width] or if the entire mask is 1, RLE is [0, height*width]. + if input_mask[i, 0] == 0: + out.append({"size": [height, width], "counts": [height * width]}) + else: + out.append({"size": [height, width], "counts": [0, height * width]}) + continue + btw_idxs = cur_idxs[1:] - cur_idxs[:-1] + counts = [] if input_mask[i, 0] == 0 else [0] + counts += [cur_idxs[0].item()] + btw_idxs.tolist() + [height * width - cur_idxs[-1].item()] + out.append({"size": [height, width], "counts": counts}) + return out + + +def _rle_to_mask(rle: dict[str, Any]) -> np.ndarray: + """Compute a binary mask from an uncompressed RLE.""" + height, width = rle["size"] + mask = np.empty(height * width, dtype=bool) + idx = 0 + parity = False + for count in rle["counts"]: + mask[idx : idx + count] = parity + idx += count + parity = not parity + mask = mask.reshape(width, height) + return mask.transpose() # Reshape to original shape + + +def _postprocess_for_mg(rle_masks, iou_scores, mask_boxes, amg_crops_nms_thresh=0.7): + """ + Perform NMS (Non Maximum Suppression) on the outputs. + + Args: + rle_masks (`torch.Tensor`): + binary masks in the RLE format + iou_scores (`torch.Tensor` of shape (nb_masks, 1)): + iou_scores predicted by the model + mask_boxes (`torch.Tensor`): + The bounding boxes corresponding to segmentation masks + amg_crops_nms_thresh (`float`, *optional*, defaults to 0.7): + NMS threshold. + """ + keep_by_nms = batched_nms( + boxes=mask_boxes.float(), + scores=iou_scores, + idxs=torch.zeros(mask_boxes.shape[0]), + iou_threshold=amg_crops_nms_thresh, + ) + + iou_scores = iou_scores[keep_by_nms] + rle_masks = [rle_masks[i] for i in keep_by_nms] + mask_boxes = mask_boxes[keep_by_nms] + masks = [_rle_to_mask(rle) for rle in rle_masks] + + return masks, iou_scores, rle_masks, mask_boxes + + +__all__ = ["SamImageProcessor"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam/image_processing_sam_fast.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam/image_processing_sam_fast.py new file mode 100644 index 0000000000000000000000000000000000000000..7e51a86bc3f98e1f58d297d4de3c31687fddfa79 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam/image_processing_sam_fast.py @@ -0,0 +1,790 @@ +# Copyright 2025 The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""Fast Image processor class for SAM.""" + +import math +from copy import deepcopy +from itertools import product +from typing import Any, Optional, Union + +import numpy as np +import torch +import torchvision.transforms.v2.functional as tvF +from torch.nn import functional as F +from torchvision.ops.boxes import batched_nms + +from ...image_processing_utils import BatchFeature, get_size_dict +from ...image_processing_utils_fast import BaseImageProcessorFast +from ...image_transforms import ( + group_images_by_shape, + reorder_images, +) +from ...image_utils import ( + IMAGENET_DEFAULT_MEAN, + IMAGENET_DEFAULT_STD, + ChannelDimension, + ImageInput, + PILImageResampling, + SizeDict, + pil_torch_interpolation_mapping, +) +from ...processing_utils import Unpack +from ...utils import ( + TensorType, + auto_docstring, +) +from .image_processing_sam import SamImageProcessorKwargs + + +@auto_docstring +class SamImageProcessorFast(BaseImageProcessorFast): + resample = PILImageResampling.BILINEAR + image_mean = IMAGENET_DEFAULT_MEAN + image_std = IMAGENET_DEFAULT_STD + size = {"longest_edge": 1024} + mask_size = {"longest_edge": 256} + do_resize = True + do_rescale = True + do_normalize = True + do_convert_rgb = True + + valid_kwargs = SamImageProcessorKwargs + + do_pad = True + pad_size = {"height": 1024, "width": 1024} + mask_pad_size = {"height": 256, "width": 256} + + def __init__(self, **kwargs: Unpack[SamImageProcessorKwargs]): + super().__init__(**kwargs) + + def _get_preprocess_shape(self, old_shape: tuple[int, int], longest_edge: int): + """ + Compute the output size given input size and target long side length. + """ + oldh, oldw = old_shape + scale = longest_edge * 1.0 / max(oldh, oldw) + newh, neww = oldh * scale, oldw * scale + newh = int(newh + 0.5) + neww = int(neww + 0.5) + return (newh, neww) + + def resize( + self, image: "torch.Tensor", size: SizeDict, interpolation: Optional["tvF.InterpolationMode"], **kwargs + ) -> "torch.Tensor": + """ + Resize an image to `(size["height"], size["width"])`. + + Args: + image (`np.ndarray`): + Image to resize. + size (`dict[str, int]`): + Dictionary in the format `{"longest_edge": int}` specifying the size of the output image. The longest + edge of the image will be resized to the specified size, while the other edge will be resized to + maintain the aspect ratio. + interpolation: + `tvF.InterpolationMode` filter to use when resizing the image e.g. `tvF.InterpolationMode.BICUBIC`. + + Returns: + `torch.Tensor`: The resized image. + """ + if not size.longest_edge: + raise ValueError(f"The `size` dictionary must contain the key `longest_edge`. Got {size.keys()}") + input_size = image.shape[-2:] + output_height, output_width = self._get_preprocess_shape(input_size, size.longest_edge) + return super().resize( + image, size=SizeDict(height=output_height, width=output_width), interpolation=interpolation, **kwargs + ) + + def _further_process_kwargs( + self, + size: SizeDict | None = None, + pad_size: SizeDict | None = None, + mask_size: SizeDict | None = None, + mask_pad_size: SizeDict | None = None, + default_to_square: bool | None = None, + image_mean: float | list[float] | None = None, + image_std: float | list[float] | None = None, + data_format: ChannelDimension | None = None, + **kwargs, + ) -> dict: + """ + Update kwargs that need further processing before being validated + Can be overridden by subclasses to customize the processing of kwargs. + """ + if kwargs is None: + kwargs = {} + if size is not None: + size = SizeDict(**get_size_dict(size=size, default_to_square=default_to_square)) + if pad_size is not None: + pad_size = SizeDict(**get_size_dict(pad_size, param_name="pad_size")) + if mask_size is not None: + mask_size = SizeDict(**get_size_dict(mask_size, param_name="mask_size")) + if mask_pad_size is not None: + mask_pad_size = SizeDict(**get_size_dict(mask_pad_size, param_name="mask_pad_size")) + if isinstance(image_mean, list): + image_mean = tuple(image_mean) + if isinstance(image_std, list): + image_std = tuple(image_std) + if data_format is None: + data_format = ChannelDimension.FIRST + + kwargs["size"] = size + kwargs["pad_size"] = pad_size + kwargs["mask_size"] = mask_size + kwargs["mask_pad_size"] = mask_pad_size + kwargs["image_mean"] = image_mean + kwargs["image_std"] = image_std + kwargs["data_format"] = data_format + + # torch resize uses interpolation instead of resample + # Check if resample is an int before checking if it's an instance of PILImageResampling + # because if pillow < 9.1.0, resample is an int and PILImageResampling is a module. + # Checking PILImageResampling will fail with error `TypeError: isinstance() arg 2 must be a type or tuple of types`. + resample = kwargs.pop("resample") + kwargs["interpolation"] = ( + pil_torch_interpolation_mapping[resample] if isinstance(resample, (PILImageResampling, int)) else resample + ) + + return kwargs + + @auto_docstring + def preprocess( + self, + images: ImageInput, + segmentation_maps: ImageInput | None = None, + **kwargs: Unpack[SamImageProcessorKwargs], + ) -> BatchFeature: + r""" + segmentation_maps (`ImageInput`, *optional*): + The segmentation maps to preprocess. + """ + return super().preprocess(images, segmentation_maps, **kwargs) + + def _preprocess_image_like_inputs( + self, + images: ImageInput, + segmentation_maps: ImageInput | None, + do_convert_rgb: bool, + input_data_format: ChannelDimension, + device: Union[str, "torch.device"] | None = None, + **kwargs: Unpack[SamImageProcessorKwargs], + ) -> BatchFeature: + """ + Preprocess image-like inputs. + """ + images = self._prepare_image_like_inputs( + images=images, do_convert_rgb=do_convert_rgb, input_data_format=input_data_format, device=device + ) + original_sizes = [image.shape[-2:] for image in images] + images_kwargs = kwargs.copy() + image_outputs = self._preprocess(images, **images_kwargs) + data = { + "pixel_values": image_outputs.pixel_values, + "original_sizes": original_sizes, + "reshaped_input_sizes": image_outputs.reshaped_input_sizes, + } + + if segmentation_maps is not None: + processed_segmentation_maps = self._prepare_image_like_inputs( + images=segmentation_maps, + expected_ndims=2, + do_convert_rgb=False, + input_data_format=ChannelDimension.FIRST, + ) + + segmentation_maps_kwargs = kwargs.copy() + segmentation_maps_kwargs.update( + { + "do_normalize": False, + "do_rescale": False, + "interpolation": tvF.InterpolationMode.NEAREST_EXACT, + "size": segmentation_maps_kwargs.pop("mask_size"), + "pad_size": segmentation_maps_kwargs.pop("mask_pad_size"), + } + ) + processed_segmentation_maps = self._preprocess( + images=processed_segmentation_maps, **segmentation_maps_kwargs + ) + data["labels"] = processed_segmentation_maps["pixel_values"].squeeze(1).to(torch.int64) + + return BatchFeature(data=data, tensor_type=kwargs["return_tensors"]) + + def _preprocess( + self, + images: list["torch.Tensor"], + do_resize: bool, + size: SizeDict, + interpolation: Optional["F.InterpolationMode"], + do_center_crop: bool, + crop_size: SizeDict, + do_rescale: bool, + rescale_factor: float, + do_normalize: bool, + image_mean: float | list[float] | None, + image_std: float | list[float] | None, + do_pad: bool | None, + pad_size: SizeDict | None, + disable_grouping: bool | None, + return_tensors: str | TensorType | None, + **kwargs, + ) -> BatchFeature: + # Group images by size for batched resizing + grouped_images, grouped_images_index = group_images_by_shape(images, disable_grouping=disable_grouping) + resized_images_grouped = {} + for shape, stacked_images in grouped_images.items(): + if do_resize: + stacked_images = self.resize(image=stacked_images, size=size, interpolation=interpolation) + resized_images_grouped[shape] = stacked_images + resized_images = reorder_images(resized_images_grouped, grouped_images_index) + reshaped_input_sizes = [image.shape[-2:] for image in resized_images] + + # Group images by size for further processing + # Needed in case do_resize is False, or resize returns images with different sizes + grouped_images, grouped_images_index = group_images_by_shape(resized_images, disable_grouping=disable_grouping) + processed_images_grouped = {} + for shape, stacked_images in grouped_images.items(): + if do_center_crop: + stacked_images = self.center_crop(stacked_images, crop_size) + # Fused rescale and normalize + stacked_images = self.rescale_and_normalize( + stacked_images, do_rescale, rescale_factor, do_normalize, image_mean, image_std + ) + processed_images_grouped[shape] = stacked_images + processed_images = reorder_images(processed_images_grouped, grouped_images_index) + + if do_pad: + processed_images = self.pad(processed_images, pad_size=pad_size, disable_grouping=disable_grouping) + + return BatchFeature( + data={"pixel_values": processed_images, "reshaped_input_sizes": reshaped_input_sizes}, + tensor_type=return_tensors, + ) + + def generate_crop_boxes( + self, + image: "torch.Tensor", + target_size, + crop_n_layers: int = 0, + overlap_ratio: float = 512 / 1500, + points_per_crop: int | None = 32, + crop_n_points_downscale_factor: list[int] | None = 1, + device: Optional["torch.device"] = None, + ): + """ + Generates a list of crop boxes of different sizes. Each layer has (2**i)**2 boxes for the ith layer. + + Args: + image (`torch.Tensor`): + Input original image + target_size (`int`): + Target size of the resized image + crop_n_layers (`int`, *optional*, defaults to 0): + If >0, mask prediction will be run again on crops of the image. Sets the number of layers to run, where + each layer has 2**i_layer number of image crops. + overlap_ratio (`float`, *optional*, defaults to 512/1500): + Sets the degree to which crops overlap. In the first crop layer, crops will overlap by this fraction of + the image length. Later layers with more crops scale down this overlap. + points_per_crop (`int`, *optional*, defaults to 32): + Number of points to sample from each crop. + crop_n_points_downscale_factor (`list[int]`, *optional*, defaults to 1): + The number of points-per-side sampled in layer n is scaled down by crop_n_points_downscale_factor**n. + device (`torch.device`, *optional*, defaults to None): + Device to use for the computation. If None, cpu will be used. + input_data_format (`str` or `ChannelDimension`, *optional*): + The channel dimension format of the input image. If not provided, it will be inferred. + return_tensors (`str`, *optional*, defaults to `pt`): + If `pt`, returns `torch.Tensor`. + """ + image = self._process_image(image) + crop_boxes, points_per_crop, cropped_images, input_labels = _generate_crop_boxes( + image, + target_size, + crop_n_layers, + overlap_ratio, + points_per_crop, + crop_n_points_downscale_factor, + ) + if device is None: + device = torch.device("cpu") + crop_boxes = crop_boxes.to(device) + points_per_crop = points_per_crop.to(device) + # cropped_images stays as torch.Tensor + input_labels = input_labels.to(device) + + return crop_boxes, points_per_crop, cropped_images, input_labels + + def filter_masks( + self, + masks, + iou_scores, + original_size, + cropped_box_image, + pred_iou_thresh=0.88, + stability_score_thresh=0.95, + mask_threshold=0, + stability_score_offset=1, + ): + """ + Filters the predicted masks by selecting only the ones that meets several criteria. The first criterion being + that the iou scores needs to be greater than `pred_iou_thresh`. The second criterion is that the stability + score needs to be greater than `stability_score_thresh`. The method also converts the predicted masks to + bounding boxes and pad the predicted masks if necessary. + + Args: + masks (`torch.Tensor`): + Input masks. + iou_scores (`torch.Tensor`): + List of IoU scores. + original_size (`tuple[int,int]`): + Size of the original image. + cropped_box_image (`torch.Tensor`): + The cropped image. + pred_iou_thresh (`float`, *optional*, defaults to 0.88): + The threshold for the iou scores. + stability_score_thresh (`float`, *optional*, defaults to 0.95): + The threshold for the stability score. + mask_threshold (`float`, *optional*, defaults to 0): + The threshold for the predicted masks. + stability_score_offset (`float`, *optional*, defaults to 1): + The offset for the stability score used in the `_compute_stability_score` method. + + """ + original_height, original_width = original_size + iou_scores = iou_scores.flatten(0, 1) + masks = masks.flatten(0, 1) + + if masks.shape[0] != iou_scores.shape[0]: + raise ValueError("masks and iou_scores must have the same batch size.") + + if masks.device != iou_scores.device: + iou_scores = iou_scores.to(masks.device) + + batch_size = masks.shape[0] + + keep_mask = torch.ones(batch_size, dtype=torch.bool, device=masks.device) + + if pred_iou_thresh > 0.0: + keep_mask = keep_mask & (iou_scores > pred_iou_thresh) + + # compute stability score + if stability_score_thresh > 0.0: + stability_scores = _compute_stability_score(masks, mask_threshold, stability_score_offset) + keep_mask = keep_mask & (stability_scores > stability_score_thresh) + + scores = iou_scores[keep_mask] + masks = masks[keep_mask] + + # binarize masks + masks = masks > mask_threshold + converted_boxes = _batched_mask_to_box(masks) + + keep_mask = ~_is_box_near_crop_edge( + converted_boxes, cropped_box_image, [0, 0, original_width, original_height] + ) + + scores = scores[keep_mask] + masks = masks[keep_mask] + converted_boxes = converted_boxes[keep_mask] + + masks = _pad_masks(masks, cropped_box_image, original_height, original_width) + # conversion to rle is necessary to run non-maximum suppression + masks = _mask_to_rle(masks) + + return masks, scores, converted_boxes + + def post_process_masks( + self, + masks, + original_sizes, + reshaped_input_sizes, + mask_threshold=0.0, + binarize=True, + pad_size=None, + ): + """ + Remove padding and upscale masks to the original image size. + + Args: + masks (`Union[List[torch.Tensor], List[np.ndarray]]`): + Batched masks from the mask_decoder in (batch_size, num_channels, height, width) format. + original_sizes (`Union[torch.Tensor, List[Tuple[int,int]]]`): + The original sizes of each image before it was resized to the model's expected input shape, in (height, + width) format. + reshaped_input_sizes (`Union[torch.Tensor, List[Tuple[int,int]]]`): + The size of each image as it is fed to the model, in (height, width) format. Used to remove padding. + mask_threshold (`float`, *optional*, defaults to 0.0): + The threshold to use for binarizing the masks. + binarize (`bool`, *optional*, defaults to `True`): + Whether to binarize the masks. + pad_size (`int`, *optional*, defaults to `self.pad_size`): + The target size the images were padded to before being passed to the model. If None, the target size is + assumed to be the processor's `pad_size`. + Returns: + (`torch.Tensor`): Batched masks in batch_size, num_channels, height, width) format, where (height, width) + is given by original_size. + """ + pad_size = self.pad_size if pad_size is None else pad_size + target_image_size = (pad_size["height"], pad_size["width"]) + if isinstance(original_sizes, (torch.Tensor, np.ndarray)): + original_sizes = original_sizes.tolist() + if isinstance(reshaped_input_sizes, (torch.Tensor, np.ndarray)): + reshaped_input_sizes = reshaped_input_sizes.tolist() + + output_masks = [] + for i, original_size in enumerate(original_sizes): + if isinstance(masks[i], np.ndarray): + masks[i] = torch.from_numpy(masks[i]) + elif not isinstance(masks[i], torch.Tensor): + raise TypeError("Input masks should be a list of `torch.tensors` or a list of `np.ndarray`") + interpolated_mask = F.interpolate(masks[i], target_image_size, mode="bilinear", align_corners=False) + interpolated_mask = interpolated_mask[..., : reshaped_input_sizes[i][0], : reshaped_input_sizes[i][1]] + interpolated_mask = F.interpolate(interpolated_mask, original_size, mode="bilinear", align_corners=False) + if binarize: + interpolated_mask = interpolated_mask > mask_threshold + output_masks.append(interpolated_mask) + + return output_masks + + def post_process_for_mask_generation(self, all_masks, all_scores, all_boxes, crops_nms_thresh): + """ + Post processes mask that are generated by calling the Non Maximum Suppression algorithm on the predicted masks. + + Args: + all_masks (`torch.Tensor`): + List of all predicted segmentation masks + all_scores (`torch.Tensor`): + List of all predicted iou scores + all_boxes (`torch.Tensor`): + List of all bounding boxes of the predicted masks + crops_nms_thresh (`float`): + Threshold for NMS (Non Maximum Suppression) algorithm. + """ + return _post_process_for_mask_generation(all_masks, all_scores, all_boxes, crops_nms_thresh) + + +def _compute_stability_score(masks: "torch.Tensor", mask_threshold: float, stability_score_offset: int): + # One mask is always contained inside the other. + # Save memory by preventing unnecessary cast to torch.int64 + intersections = ( + (masks > (mask_threshold + stability_score_offset)).sum(-1, dtype=torch.int16).sum(-1, dtype=torch.int32) + ) + unions = (masks > (mask_threshold - stability_score_offset)).sum(-1, dtype=torch.int16).sum(-1, dtype=torch.int32) + stability_scores = intersections / unions + return stability_scores + + +def _mask_to_rle(input_mask: "torch.Tensor"): + """ + Encodes masks the run-length encoding (RLE), in the format expected by pycoco tools. + """ + # Put in fortran order and flatten height and width + batch_size, height, width = input_mask.shape + input_mask = input_mask.permute(0, 2, 1).flatten(1) + + # Compute change indices + diff = input_mask[:, 1:] ^ input_mask[:, :-1] + change_indices = diff.nonzero() + + # Encode run length + out = [] + for i in range(batch_size): + cur_idxs = change_indices[change_indices[:, 0] == i, 1] + 1 + if len(cur_idxs) == 0: + # No changes => either all 0 or all 1 + # If the entire mask is 0, RLE is [height*width] or if the entire mask is 1, RLE is [0, height*width]. + if input_mask[i, 0] == 0: + out.append({"size": [height, width], "counts": [height * width]}) + else: + out.append({"size": [height, width], "counts": [0, height * width]}) + continue + btw_idxs = cur_idxs[1:] - cur_idxs[:-1] + counts = [] if input_mask[i, 0] == 0 else [0] + counts += [cur_idxs[0].item()] + btw_idxs.tolist() + [height * width - cur_idxs[-1].item()] + out.append({"size": [height, width], "counts": counts}) + return out + + +def _batched_mask_to_box(masks: "torch.Tensor"): + """ + Computes the bounding boxes around the given input masks. The bounding boxes are in the XYXY format which + corresponds the following required indices: + - LEFT: left hand side of the bounding box + - TOP: top of the bounding box + - RIGHT: right of the bounding box + - BOTTOM: bottom of the bounding box + + Return [0,0,0,0] for an empty mask. For input shape channel_1 x channel_2 x ... x height x width, the output shape + is channel_1 x channel_2 x ... x 4. + + Args: + - masks (`torch.Tensor` of shape `(batch, nb_mask, height, width)`) + """ + # torch.max below raises an error on empty inputs, just skip in this case + + if torch.numel(masks) == 0: + return torch.zeros(*masks.shape[:-2], 4, device=masks.device) + + # Normalize shape to Cxheightxwidth + shape = masks.shape + height, width = shape[-2:] + + # Get top and bottom edges + in_height, _ = torch.max(masks, dim=-1) + in_height_coords = in_height * torch.arange(height, device=in_height.device)[None, :] + bottom_edges, _ = torch.max(in_height_coords, dim=-1) + in_height_coords = in_height_coords + height * (~in_height) + top_edges, _ = torch.min(in_height_coords, dim=-1) + + # Get left and right edges + in_width, _ = torch.max(masks, dim=-2) + in_width_coords = in_width * torch.arange(width, device=in_width.device)[None, :] + right_edges, _ = torch.max(in_width_coords, dim=-1) + in_width_coords = in_width_coords + width * (~in_width) + left_edges, _ = torch.min(in_width_coords, dim=-1) + + # If the mask is empty the right edge will be to the left of the left edge. + # Replace these boxes with [0, 0, 0, 0] + empty_filter = (right_edges < left_edges) | (bottom_edges < top_edges) + out = torch.stack([left_edges, top_edges, right_edges, bottom_edges], dim=-1) + out = out * (~empty_filter).unsqueeze(-1) + + # Return to original shape + out = out.reshape(*shape[:-2], 4) + return out + + +def _is_box_near_crop_edge(boxes, crop_box, orig_box, atol=20.0): + """Filter masks at the edge of a crop, but not at the edge of the original image.""" + crop_box_torch = torch.as_tensor(crop_box, dtype=torch.float, device=boxes.device) + orig_box_torch = torch.as_tensor(orig_box, dtype=torch.float, device=boxes.device) + + left, top, _, _ = crop_box + offset = torch.tensor([[left, top, left, top]], device=boxes.device) + # Check if boxes has a channel dimension + if len(boxes.shape) == 3: + offset = offset.unsqueeze(1) + boxes = (boxes + offset).float() + + near_crop_edge = torch.isclose(boxes, crop_box_torch[None, :], atol=atol, rtol=0) + near_image_edge = torch.isclose(boxes, orig_box_torch[None, :], atol=atol, rtol=0) + near_crop_edge = torch.logical_and(near_crop_edge, ~near_image_edge) + return torch.any(near_crop_edge, dim=1) + + +def _pad_masks(masks, crop_box: list[int], orig_height: int, orig_width: int): + left, top, right, bottom = crop_box + if left == 0 and top == 0 and right == orig_width and bottom == orig_height: + return masks + # Coordinate transform masks + pad_x, pad_y = orig_width - (right - left), orig_height - (bottom - top) + pad = (left, pad_x - left, top, pad_y - top) + return torch.nn.functional.pad(masks, pad, value=0) + + +def _generate_crop_boxes( + image, + target_size: int, # Is it tuple here? + crop_n_layers: int = 0, + overlap_ratio: float = 512 / 1500, + points_per_crop: int | None = 32, + crop_n_points_downscale_factor: list[int] | None = 1, +) -> tuple[list[list[int]], list[int]]: + """ + Generates a list of crop boxes of different sizes. Each layer has (2**i)**2 boxes for the ith layer. + + Args: + image (Union[`numpy.ndarray`, `PIL.Image`, `torch.Tensor`]): + Image to generate crops for. + target_size (`int`): + Size of the smallest crop. + crop_n_layers (`int`, *optional*): + If `crops_n_layers>0`, mask prediction will be run again on crops of the image. Sets the number of layers + to run, where each layer has 2**i_layer number of image crops. + overlap_ratio (`int`, *optional*): + Sets the degree to which crops overlap. In the first crop layer, crops will overlap by this fraction of the + image length. Later layers with more crops scale down this overlap. + points_per_crop (`int`, *optional*): + Number of points to sample per crop. + crop_n_points_downscale_factor (`int`, *optional*): + The number of points-per-side sampled in layer n is scaled down by crop_n_points_downscale_factor**n. + input_data_format (`str` or `ChannelDimension`, *optional*): + The channel dimension format of the input image. If not provided, it will be inferred. + """ + + if isinstance(image, list): + raise ValueError("Only one image is allowed for crop generation.") + original_size = image.shape[-2:] + + points_grid = [] + for i in range(crop_n_layers + 1): + n_points = int(points_per_crop / (crop_n_points_downscale_factor**i)) + points_grid.append(_build_point_grid(n_points)) + + crop_boxes, layer_idxs = _generate_per_layer_crops(crop_n_layers, overlap_ratio, original_size) + + cropped_images, point_grid_per_crop = _generate_crop_images( + crop_boxes, image, points_grid, layer_idxs, target_size, original_size + ) + crop_boxes = torch.tensor(crop_boxes) + crop_boxes = crop_boxes.float() + points_per_crop = torch.stack(point_grid_per_crop) + points_per_crop = points_per_crop.unsqueeze(0).permute(0, 2, 1, 3) + cropped_images = torch.stack(cropped_images) + + input_labels = torch.ones_like(points_per_crop[:, :, :, 0], dtype=torch.int64) + + return crop_boxes, points_per_crop, cropped_images, input_labels + + +def _generate_per_layer_crops(crop_n_layers, overlap_ratio, original_size): + """ + Generates 2 ** (layers idx + 1) crops for each crop_n_layers. Crops are in the XYWH format : The XYWH format + consists of the following required indices: + - X: X coordinate of the top left of the bounding box + - Y: Y coordinate of the top left of the bounding box + - W: width of the bounding box + - H: height of the bounding box + """ + crop_boxes, layer_idxs = [], [] + im_height, im_width = original_size + short_side = min(im_height, im_width) + + # Original image + crop_boxes.append([0, 0, im_width, im_height]) + layer_idxs.append(0) + for i_layer in range(crop_n_layers): + n_crops_per_side = 2 ** (i_layer + 1) + overlap = int(overlap_ratio * short_side * (2 / n_crops_per_side)) + + crop_width = int(math.ceil((overlap * (n_crops_per_side - 1) + im_width) / n_crops_per_side)) + crop_height = int(math.ceil((overlap * (n_crops_per_side - 1) + im_height) / n_crops_per_side)) + + crop_box_x0 = [int((crop_width - overlap) * i) for i in range(n_crops_per_side)] + crop_box_y0 = [int((crop_height - overlap) * i) for i in range(n_crops_per_side)] + + for left, top in product(crop_box_x0, crop_box_y0): + box = [left, top, min(left + crop_width, im_width), min(top + crop_height, im_height)] + crop_boxes.append(box) + layer_idxs.append(i_layer + 1) + + return crop_boxes, layer_idxs + + +def _build_point_grid(n_per_side: int) -> torch.Tensor: + """Generates a 2D grid of points evenly spaced in [0,1]x[0,1].""" + offset = 1 / (2 * n_per_side) + points_one_side = torch.linspace(offset, 1 - offset, n_per_side) + points_x = torch.tile(points_one_side[None, :], (n_per_side, 1)) + points_y = torch.tile(points_one_side[:, None], (1, n_per_side)) + points = torch.stack([points_x, points_y], dim=-1).reshape(-1, 2) + return points + + +def _generate_crop_images( + crop_boxes, image, points_grid, layer_idxs, target_size, original_size, input_data_format=None +): + """ + Takes as an input bounding boxes that are used to crop the image. Based in the crops, the corresponding points are + also passed. + """ + cropped_images = [] + total_points_per_crop = [] + for i, crop_box in enumerate(crop_boxes): + left, top, right, bottom = crop_box + cropped_im = image[:, top:bottom, left:right] + + cropped_images.append(cropped_im) + + cropped_im_size = cropped_im.shape[-2:] + points_scale = torch.tensor(cropped_im_size).flip(dims=(0,)).unsqueeze(0) + + points = points_grid[layer_idxs[i]] * points_scale + normalized_points = _normalize_coordinates(target_size, points, original_size) + total_points_per_crop.append(normalized_points) + + return cropped_images, total_points_per_crop + + +def _normalize_coordinates( + target_size: int, coords: torch.Tensor, original_size: tuple[int, int], is_bounding_box=False +) -> torch.Tensor: + """ + Expects a numpy array of length 2 in the final dimension. Requires the original image size in (height, width) + format. + """ + old_height, old_width = original_size + + scale = target_size * 1.0 / max(old_height, old_width) + new_height, new_width = old_height * scale, old_width * scale + new_width = int(new_width + 0.5) + new_height = int(new_height + 0.5) + + coords = deepcopy(coords).float() + + if is_bounding_box: + coords = coords.reshape(-1, 2, 2) + + coords[..., 0] = coords[..., 0] * (new_width / old_width) + coords[..., 1] = coords[..., 1] * (new_height / old_height) + + if is_bounding_box: + coords = coords.reshape(-1, 4) + + return coords + + +def _rle_to_mask(rle: dict[str, Any]) -> torch.Tensor: + """Compute a binary mask from an uncompressed RLE.""" + height, width = rle["size"] + mask = torch.empty(height * width, dtype=bool) + idx = 0 + parity = False + for count in rle["counts"]: + mask[idx : idx + count] = parity + idx += count + parity = not parity + mask = mask.reshape(width, height) + return mask.transpose(0, 1) # Reshape to original shape + + +def _post_process_for_mask_generation(rle_masks, iou_scores, mask_boxes, amg_crops_nms_thresh=0.7): + """ + Perform NMS (Non Maximum Suppression) on the outputs. + + Args: + rle_masks (`torch.Tensor`): + binary masks in the RLE format + iou_scores (`torch.Tensor` of shape (nb_masks, 1)): + iou_scores predicted by the model + mask_boxes (`torch.Tensor`): + The bounding boxes corresponding to segmentation masks + amg_crops_nms_thresh (`float`, *optional*, defaults to 0.7): + NMS threshold. + """ + keep_by_nms = batched_nms( + boxes=mask_boxes.float(), + scores=iou_scores, + idxs=torch.zeros(mask_boxes.shape[0]), + iou_threshold=amg_crops_nms_thresh, + ) + + iou_scores = iou_scores[keep_by_nms] + rle_masks = [rle_masks[i] for i in keep_by_nms] + mask_boxes = mask_boxes[keep_by_nms] + masks = [_rle_to_mask(rle) for rle in rle_masks] + + return masks, iou_scores, rle_masks, mask_boxes + + +__all__ = ["SamImageProcessorFast"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam/modeling_sam.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam/modeling_sam.py new file mode 100644 index 0000000000000000000000000000000000000000..7638a2a8f8c0f02bba2b5b62dc9197c102e2fca5 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam/modeling_sam.py @@ -0,0 +1,1361 @@ +# Copyright 2023 The Meta AI Authors and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""PyTorch SAM model.""" + +import collections +from collections.abc import Callable +from dataclasses import dataclass + +import numpy as np +import torch +import torch.nn.functional as F +from torch import Tensor, nn + +from ... import initialization as init +from ...activations import ACT2FN +from ...modeling_layers import GradientCheckpointingLayer +from ...modeling_outputs import BaseModelOutput +from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel +from ...processing_utils import Unpack +from ...utils import ModelOutput, auto_docstring, logging +from ...utils.generic import TransformersKwargs, merge_with_config_defaults +from ...utils.output_capturing import OutputRecorder, capture_outputs +from .configuration_sam import SamConfig, SamMaskDecoderConfig, SamPromptEncoderConfig, SamVisionConfig + + +logger = logging.get_logger(__name__) + + +@dataclass +@auto_docstring( + custom_intro=""" + Base class for sam vision model's outputs that also contains image embeddings obtained by applying the projection + layer to the pooler_output. + """ +) +class SamVisionEncoderOutput(ModelOutput): + r""" + image_embeds (`torch.FloatTensor` of shape `(batch_size, output_dim)` *optional* returned when model is initialized with `with_projection=True`): + The image embeddings obtained by applying the projection layer to the pooler_output. + """ + + image_embeds: torch.FloatTensor | None = None + last_hidden_state: torch.FloatTensor | None = None + hidden_states: tuple[torch.FloatTensor, ...] | None = None + attentions: tuple[torch.FloatTensor, ...] | None = None + + +@dataclass +@auto_docstring( + custom_intro=""" + Base class for Segment-Anything model's output + """ +) +class SamImageSegmentationOutput(ModelOutput): + r""" + iou_scores (`torch.FloatTensor` of shape `(batch_size, num_masks)`): + The iou scores of the predicted masks. + pred_masks (`torch.FloatTensor` of shape `(batch_size, num_masks, height, width)`): + The predicted low resolutions masks. Needs to be post-processed by the processor + vision_hidden_states (`tuple(torch.FloatTensor)`, *optional*, returned when `output_hidden_states=True` is passed or when `config.output_hidden_states=True`): + Tuple of `torch.FloatTensor` (one for the output of the embeddings, if the model has an embedding layer, + + one for the output of each layer) of shape `(batch_size, sequence_length, hidden_size)`. + + Hidden-states of the vision model at the output of each layer plus the optional initial embedding outputs. + vision_attentions (`tuple(torch.FloatTensor)`, *optional*, returned when `output_attentions=True` is passed or when `config.output_attentions=True`): + Tuple of `torch.FloatTensor` (one for each layer) of shape `(batch_size, num_heads, sequence_length, + sequence_length)`. + + Attentions weights after the attention softmax, used to compute the weighted average in the self-attention + heads. + mask_decoder_attentions (`tuple(torch.FloatTensor)`, *optional*, returned when `output_attentions=True` is passed or when `config.output_attentions=True`): + Tuple of `torch.FloatTensor` (one for each layer) of shape `(batch_size, num_heads, sequence_length, + sequence_length)`. + + Attentions weights after the attention softmax, used to compute the weighted average in the self-attention + heads. + """ + + iou_scores: torch.FloatTensor | None = None + pred_masks: torch.FloatTensor | None = None + vision_hidden_states: tuple[torch.FloatTensor, ...] | None = None + vision_attentions: tuple[torch.FloatTensor, ...] | None = None + mask_decoder_attentions: tuple[torch.FloatTensor, ...] | None = None + + +class SamPatchEmbeddings(nn.Module): + """ + This class turns `pixel_values` of shape `(batch_size, num_channels, height, width)` into the initial + `hidden_states` (patch embeddings) of shape `(batch_size, seq_length, hidden_size)` to be consumed by a + Transformer. + """ + + def __init__(self, config): + super().__init__() + image_size, patch_size = config.image_size, config.patch_size + num_channels, hidden_size = config.num_channels, config.hidden_size + image_size = image_size if isinstance(image_size, collections.abc.Iterable) else (image_size, image_size) + patch_size = patch_size if isinstance(patch_size, collections.abc.Iterable) else (patch_size, patch_size) + num_patches = (image_size[1] // patch_size[1]) * (image_size[0] // patch_size[0]) + self.image_size = image_size + self.patch_size = patch_size + self.num_channels = num_channels + self.num_patches = num_patches + + self.projection = nn.Conv2d(num_channels, hidden_size, kernel_size=patch_size, stride=patch_size) + + def forward(self, pixel_values): + batch_size, num_channels, height, width = pixel_values.shape + if num_channels != self.num_channels: + raise ValueError( + "Make sure that the channel dimension of the pixel values match with the one set in the configuration." + ) + if height != self.image_size[0] or width != self.image_size[1]: + raise ValueError( + f"Input image size ({height}*{width}) doesn't match model ({self.image_size[0]}*{self.image_size[1]})." + ) + embeddings = self.projection(pixel_values).permute(0, 2, 3, 1) + return embeddings + + +class SamMLPBlock(nn.Module): + def __init__(self, config): + super().__init__() + self.lin1 = nn.Linear(config.hidden_size, config.mlp_dim) + self.lin2 = nn.Linear(config.mlp_dim, config.hidden_size) + self.act = ACT2FN[config.hidden_act] + + def forward(self, hidden_states: torch.Tensor) -> torch.Tensor: + hidden_states = self.lin1(hidden_states) + hidden_states = self.act(hidden_states) + hidden_states = self.lin2(hidden_states) + return hidden_states + + +# Copied from transformers.models.convnext.modeling_convnext.ConvNextLayerNorm with ConvNext->Sam +class SamLayerNorm(nn.LayerNorm): + r"""LayerNorm that supports two data formats: channels_last (default) or channels_first. + The ordering of the dimensions in the inputs. channels_last corresponds to inputs with shape (batch_size, height, + width, channels) while channels_first corresponds to inputs with shape (batch_size, channels, height, width). + """ + + def __init__(self, normalized_shape, *, eps=1e-6, data_format="channels_last", **kwargs): + super().__init__(normalized_shape, eps=eps, **kwargs) + if data_format not in ["channels_last", "channels_first"]: + raise NotImplementedError(f"Unsupported data format: {data_format}") + self.data_format = data_format + + def forward(self, features: torch.Tensor) -> torch.Tensor: + """ + Args: + features: Tensor of shape (batch_size, channels, height, width) OR (batch_size, height, width, channels) + """ + if self.data_format == "channels_first": + features = features.permute(0, 2, 3, 1) + features = super().forward(features) + features = features.permute(0, 3, 1, 2) + else: + features = super().forward(features) + return features + + +def eager_attention_forward( + module: nn.Module, + query: torch.Tensor, + key: torch.Tensor, + value: torch.Tensor, + attention_mask: torch.Tensor | None, + scaling: float, + dropout: float = 0.0, + **kwargs, +): + attn_weights = torch.matmul(query, key.transpose(2, 3)) * scaling + if attention_mask is not None: + attn_weights = attn_weights + attention_mask + + attn_weights = nn.functional.softmax(attn_weights, dim=-1, dtype=torch.float32).to(query.dtype) + attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training) + attn_output = torch.matmul(attn_weights, value) + attn_output = attn_output.transpose(1, 2).contiguous() + + return attn_output, attn_weights + + +class SamAttention(nn.Module): + """ + SAM's attention layer that allows for downscaling the size of the embedding after projection to queries, keys, and + values. + """ + + def __init__(self, config, downsample_rate=None): + super().__init__() + self.config = config + self.hidden_size = config.hidden_size + + downsample_rate = config.attention_downsample_rate if downsample_rate is None else downsample_rate + + self.internal_dim = config.hidden_size // downsample_rate + self.num_attention_heads = config.num_attention_heads + if self.internal_dim % config.num_attention_heads != 0: + raise ValueError("num_attention_heads must divide hidden_size.") + self.scaling = (self.internal_dim // config.num_attention_heads) ** -0.5 + + self.q_proj = nn.Linear(self.hidden_size, self.internal_dim) + self.k_proj = nn.Linear(self.hidden_size, self.internal_dim) + self.v_proj = nn.Linear(self.hidden_size, self.internal_dim) + self.out_proj = nn.Linear(self.internal_dim, self.hidden_size) + + self.is_causal = False + + def _separate_heads(self, hidden_states: Tensor, num_attention_heads: int) -> Tensor: + batch, point_batch_size, n_tokens, channel = hidden_states.shape + c_per_head = channel // num_attention_heads + hidden_states = hidden_states.reshape(batch * point_batch_size, n_tokens, num_attention_heads, c_per_head) + return hidden_states.transpose(1, 2) + + def _recombine_heads(self, hidden_states: Tensor, point_batch_size: int) -> Tensor: + batch, n_tokens, n_heads, c_per_head = hidden_states.shape + return hidden_states.reshape(batch // point_batch_size, point_batch_size, n_tokens, n_heads * c_per_head) + + def forward( + self, + query: Tensor, + key: Tensor, + value: Tensor, + attention_similarity: Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> Tensor: + # Input projections + query = self.q_proj(query) + key = self.k_proj(key) + value = self.v_proj(value) + + point_batch_size = query.shape[1] + # Separate into heads + query = self._separate_heads(query, self.num_attention_heads) + key = self._separate_heads(key, self.num_attention_heads) + value = self._separate_heads(value, self.num_attention_heads) + + # SamAttention + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, eager_attention_forward + ) + + attn_output, attn_weights = attention_interface( + self, + query, + key, + value, + attention_mask=attention_similarity, + dropout=0.0, + scaling=self.scaling, + is_causal=self.is_causal, + **kwargs, + ) + + attn_output = self._recombine_heads(attn_output, point_batch_size) + attn_output = self.out_proj(attn_output) + + return attn_output, attn_weights + + +class SamTwoWayAttentionBlock(nn.Module): + def __init__(self, config, attention_downsample_rate: int = 2, skip_first_layer_pe: bool = False): + """ + A transformer block with four layers: + (1) self-attention of sparse inputs (2) cross attention of sparse inputs -> dense inputs (3) mlp block on + sparse inputs (4) cross attention of dense inputs -> sparse inputs + + Arguments: + config (`SamMaskDecoderConfig`): + The configuration file used to instantiate the block + attention_downsample_rate (*optionalk*, int, defaults to 2): + The downsample ratio of the block used to reduce the inner dim of the attention. + skip_first_layer_pe (*optional*, bool, defaults to `False`): + Whether or not to skip the addition of the query_point_embedding on the first layer. + """ + super().__init__() + + self.hidden_size = config.hidden_size + self.layer_norm_eps = config.layer_norm_eps + + self.self_attn = SamAttention(config, downsample_rate=1) + self.layer_norm1 = nn.LayerNorm(self.hidden_size, eps=self.layer_norm_eps) + + self.cross_attn_token_to_image = SamAttention(config, downsample_rate=attention_downsample_rate) + self.layer_norm2 = nn.LayerNorm(self.hidden_size, eps=self.layer_norm_eps) + + self.mlp = SamMLPBlock(config) + self.layer_norm3 = nn.LayerNorm(self.hidden_size, eps=self.layer_norm_eps) + + self.layer_norm4 = nn.LayerNorm(self.hidden_size, eps=self.layer_norm_eps) + self.cross_attn_image_to_token = SamAttention(config, downsample_rate=attention_downsample_rate) + self.skip_first_layer_pe = skip_first_layer_pe + + def forward( + self, + queries: Tensor, + keys: Tensor, + query_point_embedding: Tensor, + key_point_embedding: Tensor, + attention_similarity: Tensor, + **kwargs: Unpack[TransformersKwargs], + ): + # Self attention block + if self.skip_first_layer_pe: + queries, _ = self.self_attn(query=queries, key=queries, value=queries) + else: + query = queries + query_point_embedding + attn_out, _ = self.self_attn(query=query, key=query, value=queries) + queries = queries + attn_out + queries = self.layer_norm1(queries) + + # Cross attention block, tokens attending to image embedding + query = queries + query_point_embedding + key = keys + key_point_embedding + + attn_out, _ = self.cross_attn_token_to_image( + query=query, key=key, value=keys, attention_similarity=attention_similarity + ) + queries = queries + attn_out + + queries = self.layer_norm2(queries) + + # MLP block + mlp_out = self.mlp(queries) + queries = queries + mlp_out + queries = self.layer_norm3(queries) + + # Cross attention block, image embedding attending to tokens + query = queries + query_point_embedding + key = keys + key_point_embedding + + attn_out, _ = self.cross_attn_image_to_token(query=key, key=query, value=queries) + keys = keys + attn_out + + keys = self.layer_norm4(keys) + return queries, keys, attn_out + + +class SamTwoWayTransformer(nn.Module): + def __init__(self, config: SamMaskDecoderConfig): + super().__init__() + self.config = config + + self.num_hidden_layers = config.num_hidden_layers + self.layers = nn.ModuleList() + + for i in range(self.num_hidden_layers): + self.layers.append(SamTwoWayAttentionBlock(config, skip_first_layer_pe=(i == 0))) + + self.final_attn_token_to_image = SamAttention(config) + self.layer_norm_final_attn = nn.LayerNorm(config.hidden_size) + + def forward( + self, + point_embeddings: Tensor, + image_embeddings: Tensor, + image_positional_embeddings: Tensor, + attention_similarity: Tensor, + target_embedding=None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple | BaseModelOutput: + if image_embeddings is None: + raise ValueError("You have to specify an image_embedding") + + image_embeddings = image_embeddings.flatten(2).permute(0, 2, 1).unsqueeze(1) + image_positional_embeddings = image_positional_embeddings.flatten(2).permute(0, 2, 1).unsqueeze(1) + + # Prepare queries + queries = point_embeddings + keys = image_embeddings + + # Apply transformer blocks and final layernorm + for layer in self.layers: + if target_embedding is not None: + queries += target_embedding + + queries, keys, _ = layer( + queries=queries, + keys=keys, + query_point_embedding=point_embeddings, + key_point_embedding=image_positional_embeddings, + attention_similarity=attention_similarity, + **kwargs, + ) + # Apply the final attention layer from the points to the image + query = queries + point_embeddings + key = keys + image_positional_embeddings + + attn_out, _ = self.final_attn_token_to_image(query=query, key=key, value=keys) + + queries = queries + attn_out + queries = self.layer_norm_final_attn(queries) + return queries, keys + + +class SamFeedForward(nn.Module): + def __init__( + self, input_dim: int, hidden_dim: int, output_dim: int, num_layers: int, sigmoid_output: bool = False + ): + super().__init__() + self.num_layers = num_layers + self.activation = nn.ReLU() + self.proj_in = nn.Linear(input_dim, hidden_dim) + self.proj_out = nn.Linear(hidden_dim, output_dim) + self.layers = nn.ModuleList([nn.Linear(hidden_dim, hidden_dim) for _ in range(num_layers - 2)]) + self.sigmoid_output = sigmoid_output + + def forward(self, hidden_states): + hidden_states = self.proj_in(hidden_states) + hidden_states = self.activation(hidden_states) + for layer in self.layers: + hidden_states = self.activation(layer(hidden_states)) + + hidden_states = self.proj_out(hidden_states) + if self.sigmoid_output: + hidden_states = F.sigmoid(hidden_states) + return hidden_states + + +class SamMaskDecoder(nn.Module): + def __init__(self, config: SamMaskDecoderConfig): + super().__init__() + self.config = config + self.hidden_size = config.hidden_size + + self.num_multimask_outputs = config.num_multimask_outputs + self.num_mask_tokens = config.num_multimask_outputs + 1 + + self.iou_token = nn.Embedding(1, self.hidden_size) + self.mask_tokens = nn.Embedding(self.num_mask_tokens, self.hidden_size) + + self.transformer = SamTwoWayTransformer(config) + + # should we create a new class for this? + self.upscale_conv1 = nn.ConvTranspose2d(self.hidden_size, self.hidden_size // 4, kernel_size=2, stride=2) + self.upscale_conv2 = nn.ConvTranspose2d(self.hidden_size // 4, self.hidden_size // 8, kernel_size=2, stride=2) + self.upscale_layer_norm = SamLayerNorm(self.hidden_size // 4, data_format="channels_first") + self.activation = nn.GELU() + + mlps_list = [] + for _ in range(self.num_mask_tokens): + mlps_list += [SamFeedForward(self.hidden_size, self.hidden_size, self.hidden_size // 8, 3)] + self.output_hypernetworks_mlps = nn.ModuleList(mlps_list) + + self.iou_prediction_head = SamFeedForward( + self.hidden_size, config.iou_head_hidden_dim, self.num_mask_tokens, config.iou_head_depth + ) + + def forward( + self, + image_embeddings: torch.Tensor, + image_positional_embeddings: torch.Tensor, + sparse_prompt_embeddings: torch.Tensor, + dense_prompt_embeddings: torch.Tensor, + multimask_output: bool, + attention_similarity: torch.Tensor | None = None, + target_embedding: torch.Tensor | None = None, + ) -> tuple[torch.Tensor, torch.Tensor]: + """ + Predict masks given image and prompt embeddings. + + Args: + image_embeddings (`torch.Tensor`): + the embeddings from the image encoder + image_positional_embedding (`torch.Tensor`): + positional encoding with the shape of image_embeddings + sparse_prompt_embeddings (`torch.Tensor`): + The embeddings of the points and boxes + dense_prompt_embeddings (`torch.Tensor`): + the embeddings of the mask inputs + multimask_output (bool): + Whether to return multiple masks or a single mask. + """ + batch_size, num_channels, height, width = image_embeddings.shape + point_batch_size = sparse_prompt_embeddings.shape[1] if sparse_prompt_embeddings is not None else 1 + # Concatenate output tokens + output_tokens = torch.cat([self.iou_token.weight, self.mask_tokens.weight], dim=0) + output_tokens = output_tokens.repeat(batch_size, point_batch_size, 1, 1) + + if sparse_prompt_embeddings is not None: + tokens = torch.cat((output_tokens, sparse_prompt_embeddings), dim=2) + else: + tokens = output_tokens + point_embeddings = tokens.to(self.iou_token.weight.dtype) + + # Expand per-image data in batch direction to be per-point + image_embeddings = image_embeddings + dense_prompt_embeddings + image_embeddings = image_embeddings.repeat_interleave(point_batch_size, 0) + image_positional_embeddings = image_positional_embeddings.repeat_interleave(point_batch_size, 0) + + # Run the transformer, image_positional_embedding are consumed + point_embedding, image_embeddings = self.transformer( + point_embeddings=point_embeddings, + image_embeddings=image_embeddings, + image_positional_embeddings=image_positional_embeddings, + attention_similarity=attention_similarity, + target_embedding=target_embedding, + ) + iou_token_out = point_embedding[:, :, 0, :] + mask_tokens_out = point_embedding[:, :, 1 : (1 + self.num_mask_tokens), :] + + # Upscale mask embeddings and predict masks using the mask tokens + image_embeddings = image_embeddings.transpose(2, 3).reshape( + batch_size * point_batch_size, num_channels, height, width + ) + + upscaled_embedding = self.upscale_conv1(image_embeddings) + upscaled_embedding = self.activation(self.upscale_layer_norm(upscaled_embedding)) + upscaled_embedding = self.activation(self.upscale_conv2(upscaled_embedding)) + + hyper_in_list = [] + for i in range(self.num_mask_tokens): + current_mlp = self.output_hypernetworks_mlps[i] + hyper_in_list += [current_mlp(mask_tokens_out[:, :, i, :])] + hyper_in = torch.stack(hyper_in_list, dim=2) + + _, num_channels, height, width = upscaled_embedding.shape + upscaled_embedding = upscaled_embedding.reshape(batch_size, point_batch_size, num_channels, height * width) + masks = (hyper_in @ upscaled_embedding).reshape(batch_size, point_batch_size, -1, height, width) + + # Generate mask quality predictions + iou_pred = self.iou_prediction_head(iou_token_out) + + # Select the correct mask or masks for output + if multimask_output: + mask_slice = slice(1, None) + else: + mask_slice = slice(0, 1) + masks = masks[:, :, mask_slice, :, :] + iou_pred = iou_pred[:, :, mask_slice] + return masks, iou_pred + + +class SamPositionalEmbedding(nn.Module): + def __init__(self, config): + super().__init__() + self.scale = config.scale + self.positional_embedding = nn.Parameter(self.scale * torch.randn((2, config.num_pos_feats))) + + def forward(self, input_coords, input_shape=None): + """Positionally encode points that are normalized to [0,1].""" + coordinates = input_coords.clone() + + if input_shape is not None: + coordinates[:, :, :, 0] = coordinates[:, :, :, 0] / input_shape[1] + coordinates[:, :, :, 1] = coordinates[:, :, :, 1] / input_shape[0] + + # assuming coords are in [0, 1]^2 square and have d_1 x ... x d_n x 2 shape + coordinates = 2 * coordinates - 1 + coordinates = coordinates.to(self.positional_embedding.dtype) + coordinates = coordinates @ self.positional_embedding + coordinates = 2 * np.pi * coordinates + # outputs d_1 x ... x d_n x channel shape + return torch.cat([torch.sin(coordinates), torch.cos(coordinates)], dim=-1) + + +class SamMaskEmbedding(nn.Module): + def __init__(self, config: SamPromptEncoderConfig): + super().__init__() + self.mask_input_channels = config.mask_input_channels // 4 + self.activation = ACT2FN[config.hidden_act] + self.conv1 = nn.Conv2d(1, self.mask_input_channels, kernel_size=2, stride=2) + self.conv2 = nn.Conv2d(self.mask_input_channels, config.mask_input_channels, kernel_size=2, stride=2) + self.conv3 = nn.Conv2d(config.mask_input_channels, config.hidden_size, kernel_size=1) + self.layer_norm1 = SamLayerNorm( + self.mask_input_channels, eps=config.layer_norm_eps, data_format="channels_first" + ) + self.layer_norm2 = SamLayerNorm( + self.mask_input_channels * 4, eps=config.layer_norm_eps, data_format="channels_first" + ) + + def forward(self, masks): + hidden_states = self.conv1(masks) + hidden_states = self.layer_norm1(hidden_states) + hidden_states = self.activation(hidden_states) + + hidden_states = self.conv2(hidden_states) + hidden_states = self.layer_norm2(hidden_states) + hidden_states = self.activation(hidden_states) + dense_embeddings = self.conv3(hidden_states) + return dense_embeddings + + +class SamPromptEncoder(nn.Module): + def __init__(self, config: SamConfig): + super().__init__() + self.shared_embedding = SamPositionalEmbedding(config.vision_config) + config = config.prompt_encoder_config + self.mask_embed = SamMaskEmbedding(config) + self.no_mask_embed = nn.Embedding(1, config.hidden_size) + + self.image_embedding_size = (config.image_embedding_size, config.image_embedding_size) + self.input_image_size = config.image_size + + self.point_embed = nn.ModuleList( + [nn.Embedding(1, config.hidden_size) for i in range(config.num_point_embeddings)] + ) + self.hidden_size = config.hidden_size + self.not_a_point_embed = nn.Embedding(1, config.hidden_size) + + def _embed_points(self, points: torch.Tensor, labels: torch.Tensor, pad: bool) -> torch.Tensor: + """Embeds point prompts.""" + points = points + 0.5 # Shift to center of pixel + if pad: + target_point_shape = (points.shape[0], points.shape[1], 1, points.shape[-1]) + target_labels_shape = (points.shape[0], points.shape[1], 1) + padding_point = torch.zeros(target_point_shape, device=points.device) + padding_label = -torch.ones(target_labels_shape, device=labels.device) + points = torch.cat([points, padding_point], dim=2) + labels = torch.cat([labels, padding_label], dim=2) + input_shape = (self.input_image_size, self.input_image_size) + point_embedding = self.shared_embedding(points, input_shape) + + # torch.where and expanding the labels tensor is required by the ONNX export + point_embedding = torch.where(labels[..., None] == -1, self.not_a_point_embed.weight, point_embedding) + + # This is required for the ONNX export. The dtype, device need to be explicitly + # specified as otherwise torch.onnx.export interprets as double + point_embedding = torch.where(labels[..., None] != -10, point_embedding, torch.zeros_like(point_embedding)) + + point_embedding = torch.where( + (labels == 0)[:, :, :, None], + point_embedding + self.point_embed[0].weight[None, None, :, :], + point_embedding, + ) + + point_embedding = torch.where( + (labels == 1)[:, :, :, None], + point_embedding + self.point_embed[1].weight[None, None, :, :], + point_embedding, + ) + + return point_embedding + + def _embed_boxes(self, boxes: torch.Tensor) -> torch.Tensor: + """Embeds box prompts.""" + boxes = boxes + 0.5 # Shift to center of pixel + batch_size, nb_boxes = boxes.shape[:2] + coords = boxes.reshape(batch_size, nb_boxes, 2, 2) + input_shape = (self.input_image_size, self.input_image_size) + corner_embedding = self.shared_embedding(coords, input_shape) + corner_embedding[:, :, 0, :] += self.point_embed[2].weight + corner_embedding[:, :, 1, :] += self.point_embed[3].weight + return corner_embedding + + def forward( + self, + input_points: tuple[torch.Tensor, torch.Tensor] | None, + input_labels: torch.Tensor | None, + input_boxes: torch.Tensor | None, + input_masks: torch.Tensor | None, + ) -> tuple[torch.Tensor, torch.Tensor]: + """ + Embeds different types of prompts, returning both sparse and dense embeddings. + + Args: + points (`torch.Tensor`, *optional*): + point coordinates and labels to embed. + boxes (`torch.Tensor`, *optional*): + boxes to embed + masks (`torch.Tensor`, *optional*): + masks to embed + """ + sparse_embeddings = None + batch_size = 1 + if input_points is not None: + batch_size = input_points.shape[0] + if input_labels is None: + raise ValueError("If points are provided, labels must also be provided.") + point_embeddings = self._embed_points(input_points, input_labels, pad=(input_boxes is None)) + sparse_embeddings = point_embeddings + if input_boxes is not None: + batch_size = input_boxes.shape[0] + box_embeddings = self._embed_boxes(input_boxes) + if sparse_embeddings is None: + sparse_embeddings = box_embeddings + else: + sparse_embeddings = torch.cat([sparse_embeddings, box_embeddings], dim=2) + if input_masks is not None: + dense_embeddings = self.mask_embed(input_masks) + else: + dense_embeddings = self.no_mask_embed.weight.reshape(1, -1, 1, 1).expand( + batch_size, -1, self.image_embedding_size[0], self.image_embedding_size[1] + ) + + return sparse_embeddings, dense_embeddings + + +class SamVisionAttention(nn.Module): + """Multi-head Attention block with relative position embeddings.""" + + def __init__(self, config, window_size): + super().__init__() + input_size = ( + (config.image_size // config.patch_size, config.image_size // config.patch_size) + if window_size == 0 + else (window_size, window_size) + ) + + self.num_attention_heads = config.num_attention_heads + head_dim = config.hidden_size // config.num_attention_heads + self.scale = head_dim**-0.5 + self.dropout = config.attention_dropout + + self.qkv = nn.Linear(config.hidden_size, config.hidden_size * 3, bias=config.qkv_bias) + self.proj = nn.Linear(config.hidden_size, config.hidden_size) + + self.use_rel_pos = config.use_rel_pos + if self.use_rel_pos: + if input_size is None: + raise ValueError("Input size must be provided if using relative positional encoding.") + + # initialize relative positional embeddings + self.rel_pos_h = nn.Parameter(torch.zeros(2 * input_size[0] - 1, head_dim)) + self.rel_pos_w = nn.Parameter(torch.zeros(2 * input_size[1] - 1, head_dim)) + + def get_rel_pos(self, q_size: int, k_size: int, rel_pos: torch.Tensor) -> torch.Tensor: + """ + Get relative positional embeddings according to the relative positions of + query and key sizes. + + Args: + q_size (int): + size of the query. + k_size (int): + size of key k. + rel_pos (`torch.Tensor`): + relative position embeddings (L, channel). + + Returns: + Extracted positional embeddings according to relative positions. + """ + max_rel_dist = int(2 * max(q_size, k_size) - 1) + # Interpolate rel pos. + rel_pos_resized = F.interpolate( + rel_pos.reshape(1, rel_pos.shape[0], -1).permute(0, 2, 1), + size=max_rel_dist, + mode="linear", + ) + rel_pos_resized = rel_pos_resized.reshape(-1, max_rel_dist).permute(1, 0) + + # Scale the coords with short length if shapes for q and k are different. + q_coords = torch.arange(q_size)[:, None] * max(k_size / q_size, 1.0) + k_coords = torch.arange(k_size)[None, :] * max(q_size / k_size, 1.0) + relative_coords = (q_coords - k_coords) + (k_size - 1) * max(q_size / k_size, 1.0) + + return rel_pos_resized[relative_coords.long()] + + def get_decomposed_rel_pos( + self, + query: torch.Tensor, + rel_pos_h: torch.Tensor, + rel_pos_w: torch.Tensor, + q_size: tuple[int, int], + k_size: tuple[int, int], + ) -> torch.Tensor: + """ + Calculate decomposed Relative Positional Embeddings from :paper:`mvitv2`. + https://github.com/facebookresearch/mvit/blob/19786631e330df9f3622e5402b4a419a263a2c80/mvit/models/attention.py + + Args: + query (`torch.Tensor`): + query q in the attention layer with shape (batch_size, query_height * query_width, channel). + rel_pos_h (`torch.Tensor`): + relative position embeddings (Lh, channel) for height axis. + rel_pos_w (`torch.Tensor`): + relative position embeddings (Lw, channel) for width axis. + q_size (tuple): + spatial sequence size of query q with (query_height, query_width). + k_size (tuple): + spatial sequence size of key k with (key_height, key_width). + + Returns: + decomposed_rel_pos (`torch.Tensor`): + decomposed relative position embeddings. + """ + query_height, query_width = q_size + key_height, key_width = k_size + relative_position_height = self.get_rel_pos(query_height, key_height, rel_pos_h) + relative_position_width = self.get_rel_pos(query_width, key_width, rel_pos_w) + + batch_size, _, dim = query.shape + reshaped_query = query.reshape(batch_size, query_height, query_width, dim) + rel_h = torch.einsum("bhwc,hkc->bhwk", reshaped_query, relative_position_height) + rel_w = torch.einsum("bhwc,wkc->bhwk", reshaped_query, relative_position_width) + + decomposed_rel_pos = rel_h[:, :, :, :, None] + rel_w[:, :, :, None, :] + + return decomposed_rel_pos + + def forward(self, hidden_states: torch.Tensor, output_attentions=None) -> tuple[torch.Tensor, torch.Tensor]: + batch_size, height, width, _ = hidden_states.shape + # qkv with shape (3, batch_size, nHead, height * width, channel) + qkv = ( + self.qkv(hidden_states) + .reshape(batch_size, height * width, 3, self.num_attention_heads, -1) + .permute(2, 0, 3, 1, 4) + ) + # q, k, v with shape (batch_size * nHead, height * width, channel) + query, key, value = qkv.reshape(3, batch_size * self.num_attention_heads, height * width, -1).unbind(0) + + attn_weights = (query * self.scale) @ key.transpose(-2, -1) + + if self.use_rel_pos: + decomposed_rel_pos = self.get_decomposed_rel_pos( + query, self.rel_pos_h, self.rel_pos_w, (height, width), (height, width) + ) + decomposed_rel_pos = decomposed_rel_pos.reshape_as(attn_weights) + attn_weights = attn_weights + decomposed_rel_pos + + attn_weights = torch.nn.functional.softmax(attn_weights, dtype=torch.float32, dim=-1).to(query.dtype) + + attn_probs = nn.functional.dropout(attn_weights, p=self.dropout, training=self.training) + + attn_output = (attn_probs @ value).reshape(batch_size, self.num_attention_heads, height, width, -1) + attn_output = attn_output.permute(0, 2, 3, 1, 4).reshape(batch_size, height, width, -1) + + attn_output = self.proj(attn_output) + return attn_output, attn_weights + + +class SamVisionSdpaAttention(SamVisionAttention): + """ + Multi-head Attention block with relative position embeddings. + Using SDPA instead of the default attention. + """ + + def __init__(self, config, window_size): + super().__init__(config, window_size) + + def forward(self, hidden_states: torch.Tensor, output_attentions=False) -> torch.Tensor: + if output_attentions: + logger.warning_once( + f"{self.__class__.__name__} does not support `output_attentions=True`. The returned attention weights will " + "be `None`. If you want to get attention weights, please set `attn_implementation='eager'` when loading the model." + ) + batch_size, height, width, _ = hidden_states.shape + # qkv with shape (3, B, nHead, H * W, C) + qkv = ( + self.qkv(hidden_states) + .reshape(batch_size, height * width, 3, self.num_attention_heads, -1) + .permute(2, 0, 3, 1, 4) + ) + # q, k, v with shape (B * nHead, H * W, C) + query, key, value = qkv.reshape(3, batch_size * self.num_attention_heads, height * width, -1).unbind(0) + + attn_bias = None + if self.use_rel_pos: + decomposed_rel_pos = self.get_decomposed_rel_pos( + query, self.rel_pos_h, self.rel_pos_w, (height, width), (height, width) + ) + decomposed_rel_pos = decomposed_rel_pos.reshape( + batch_size, self.num_attention_heads, height * width, height * width + ) + attn_bias = decomposed_rel_pos + + query = query.view(batch_size, self.num_attention_heads, height * width, -1) + key = key.view(batch_size, self.num_attention_heads, height * width, -1) + value = value.view(batch_size, self.num_attention_heads, height * width, -1) + + attn_output = torch.nn.functional.scaled_dot_product_attention(query, key, value, attn_mask=attn_bias) + + attn_output = ( + attn_output.view(batch_size, self.num_attention_heads, height, width, -1) + .permute(0, 2, 3, 1, 4) + .reshape(batch_size, height, width, -1) + ) + + attn_output = self.proj(attn_output) + return attn_output, None + + +SAM_VISION_ATTENTION_CLASSES = { + "eager": SamVisionAttention, + "sdpa": SamVisionSdpaAttention, +} + + +class SamVisionLayer(GradientCheckpointingLayer): + def __init__(self, config, window_size): + super().__init__() + self.layer_norm1 = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps) + self.attn = SAM_VISION_ATTENTION_CLASSES[config._attn_implementation](config, window_size) + self.layer_norm2 = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps) + self.mlp = SamMLPBlock(config) + self.window_size = window_size + + def window_partition(self, hidden_states: torch.Tensor, window_size: int) -> tuple[torch.Tensor, tuple[int, int]]: + """ + Args: + Partition into non-overlapping windows with padding if needed. + hidden_states (tensor): input tokens with [batch_size, height, width, channel]. window_size (int): window + size. + + Returns: + windows: windows after partition with [batch_size * num_windows, window_size, window_size, channel]. + (pad_height, pad_width): padded height and width before partition + """ + batch_size, height, width, channel = hidden_states.shape + + pad_h = (window_size - height % window_size) % window_size + pad_w = (window_size - width % window_size) % window_size + hidden_states = F.pad(hidden_states, (0, 0, 0, pad_w, 0, pad_h)) + pad_height, pad_width = height + pad_h, width + pad_w + + hidden_states = hidden_states.reshape( + batch_size, pad_height // window_size, window_size, pad_width // window_size, window_size, channel + ) + windows = hidden_states.permute(0, 1, 3, 2, 4, 5).contiguous().reshape(-1, window_size, window_size, channel) + return windows, (pad_height, pad_width) + + def window_unpartition( + self, windows: torch.Tensor, window_size: int, padding_shape: tuple[int, int], original_shape: tuple[int, int] + ) -> torch.Tensor: + """ + Args: + Window unpartition into original sequences and removing padding. + hidden_states (tensor): + input tokens with [batch_size * num_windows, window_size, window_size, channel]. + window_size (int): + window size. + padding_shape (Tuple): + padded height and width (pad_height, pad_width). + original_shape (Tuple): original height and width (height, width) before padding. + + Returns: + hidden_states: unpartitioned sequences with [batch_size, height, width, channel]. + """ + pad_height, pad_width = padding_shape + height, width = original_shape + batch_size = windows.shape[0] // (pad_height * pad_width // window_size // window_size) + hidden_states = windows.reshape( + batch_size, pad_height // window_size, pad_width // window_size, window_size, window_size, -1 + ) + hidden_states = ( + hidden_states.permute(0, 1, 3, 2, 4, 5).contiguous().reshape(batch_size, pad_height, pad_width, -1) + ) + + hidden_states = hidden_states[:, :height, :width, :].contiguous() + return hidden_states + + def forward(self, hidden_states: torch.Tensor) -> tuple[torch.FloatTensor]: + residual = hidden_states + hidden_states = self.layer_norm1(hidden_states) + # Window partition + if self.window_size > 0: + height, width = hidden_states.shape[1], hidden_states.shape[2] + hidden_states, padding_shape = self.window_partition(hidden_states, self.window_size) + + hidden_states, attn_weights = self.attn( + hidden_states=hidden_states, + ) + # Reverse window partition + if self.window_size > 0: + hidden_states = self.window_unpartition(hidden_states, self.window_size, padding_shape, (height, width)) + + hidden_states = residual + hidden_states + layernorm_output = self.layer_norm2(hidden_states) + hidden_states = hidden_states + self.mlp(layernorm_output) + return hidden_states + + +class SamVisionNeck(nn.Module): + def __init__(self, config: SamVisionConfig): + super().__init__() + self.config = config + + self.conv1 = nn.Conv2d(config.hidden_size, config.output_channels, kernel_size=1, bias=False) + self.layer_norm1 = SamLayerNorm(config.output_channels, data_format="channels_first") + self.conv2 = nn.Conv2d(config.output_channels, config.output_channels, kernel_size=3, padding=1, bias=False) + self.layer_norm2 = SamLayerNorm(config.output_channels, data_format="channels_first") + + def forward(self, hidden_states): + hidden_states = hidden_states.permute(0, 3, 1, 2) + hidden_states = self.conv1(hidden_states) + hidden_states = self.layer_norm1(hidden_states) + + hidden_states = self.conv2(hidden_states) + hidden_states = self.layer_norm2(hidden_states) + return hidden_states + + +@auto_docstring +class SamPreTrainedModel(PreTrainedModel): + config: SamConfig + base_model_prefix = "sam" + main_input_name = "pixel_values" + input_modalities = ("image",) + _no_split_modules = ["SamVisionAttention"] + supports_gradient_checkpointing = True + _supports_sdpa = True + + @torch.no_grad() + def _init_weights(self, module: nn.Module): + super()._init_weights(module) + if isinstance(module, SamVisionAttention): + if module.use_rel_pos: + init.zeros_(module.rel_pos_h) + init.zeros_(module.rel_pos_w) + elif isinstance(module, SamVisionEncoder): + if self.config.use_abs_pos: + init.zeros_(module.pos_embed) + elif isinstance(module, SamPositionalEmbedding): + init.normal_(module.positional_embedding, std=module.scale) + + +class SamVisionEncoder(SamPreTrainedModel): + _can_record_outputs = {"hidden_states": SamVisionLayer, "attentions": SamVisionAttention} + + def __init__(self, config: SamVisionConfig): + super().__init__(config) + self.config = config + self.image_size = config.image_size + self.patch_embed = SamPatchEmbeddings(config) + + self.pos_embed = None + if config.use_abs_pos: + # Initialize absolute positional embedding with pretrain image size. + self.pos_embed = nn.Parameter( + torch.zeros( + 1, + config.image_size // config.patch_size, + config.image_size // config.patch_size, + config.hidden_size, + ) + ) + + self.layers = nn.ModuleList() + for i in range(config.num_hidden_layers): + layer = SamVisionLayer( + config, + window_size=config.window_size if i not in config.global_attn_indexes else 0, + ) + self.layers.append(layer) + + self.neck = SamVisionNeck(config) + + self.gradient_checkpointing = False + self.post_init() + + def get_input_embeddings(self): + return self.patch_embed + + @merge_with_config_defaults + @capture_outputs(tie_last_hidden_states=False) + def forward( + self, pixel_values: torch.FloatTensor | None = None, **kwargs: Unpack[TransformersKwargs] + ) -> tuple | SamVisionEncoderOutput: + if pixel_values is None: + raise ValueError("You have to specify pixel_values") + + hidden_states = self.patch_embed(pixel_values) + if self.pos_embed is not None: + hidden_states = hidden_states + self.pos_embed + for layer_module in self.layers: + hidden_states = layer_module(hidden_states) + hidden_states = self.neck(hidden_states) + return SamVisionEncoderOutput( + last_hidden_state=hidden_states, + ) + + +@auto_docstring( + custom_intro=""" + The vision model from Sam without any head or projection on top. + """ +) +class SamVisionModel(SamPreTrainedModel): + config: SamVisionConfig + main_input_name = "pixel_values" + + def __init__(self, config: SamVisionConfig): + super().__init__(config) + self.vision_encoder = SamVisionEncoder(config) + self.post_init() + + def get_input_embeddings(self) -> nn.Module: + return self.vision_encoder.patch_embed + + @auto_docstring + def forward( + self, + pixel_values: torch.FloatTensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple | SamVisionEncoderOutput: + return self.vision_encoder(pixel_values, **kwargs) + + +@auto_docstring( + custom_intro=""" + Segment Anything Model (SAM) for generating segmentation masks, given an input image and + input points and labels, boxes, or masks. + """ +) +class SamModel(SamPreTrainedModel): + input_modalities = ("image", "text") + _can_record_outputs = {"mask_decoder_attentions": OutputRecorder(SamTwoWayAttentionBlock, index=2)} + _tied_weights_keys = { + "prompt_encoder.shared_embedding.positional_embedding": "shared_image_embedding.positional_embedding" + } + + def __init__(self, config: SamConfig): + super().__init__(config) + self.shared_image_embedding = SamPositionalEmbedding(config.vision_config) + + self.vision_encoder = SamVisionEncoder(config.vision_config) + self.prompt_encoder = SamPromptEncoder(config) + # The module using it is not a PreTrainedModel subclass so we need this + config.mask_decoder_config._attn_implementation = config._attn_implementation + self.mask_decoder = SamMaskDecoder(config.mask_decoder_config) + self.post_init() + + def get_input_embeddings(self): + return self.vision_encoder.get_input_embeddings() + + def get_image_wide_positional_embeddings(self): + size = self.config.prompt_encoder_config.image_embedding_size + target_device = self.shared_image_embedding.positional_embedding.device + target_dtype = self.shared_image_embedding.positional_embedding.dtype + grid = torch.ones((size, size), device=target_device, dtype=target_dtype) + y_embed = grid.cumsum(dim=0) - 0.5 + x_embed = grid.cumsum(dim=1) - 0.5 + y_embed = y_embed / size + x_embed = x_embed / size + + positional_embedding = self.shared_image_embedding(torch.stack([x_embed, y_embed], dim=-1)) + return positional_embedding.permute(2, 0, 1).unsqueeze(0) # channel x height x width + + @torch.no_grad() + def get_image_embeddings(self, pixel_values, **kwargs: Unpack[TransformersKwargs]): + r""" + Returns the image embeddings by passing the pixel values through the vision encoder. + + Args: + pixel_values (`torch.FloatTensor` of shape `(batch_size, num_channels, height, width)`): + Input pixel values + """ + vision_output = self.vision_encoder( + pixel_values, + **kwargs, + ) + image_embeddings = vision_output[0] + return image_embeddings + + @torch.no_grad() + def get_prompt_embeddings( + self, + input_points: torch.FloatTensor | None = None, + input_labels: torch.LongTensor | None = None, + input_boxes: torch.FloatTensor | None = None, + input_masks: torch.LongTensor | None = None, + ): + r""" + Returns the prompt embeddings by passing the input points, labels, boxes and masks through the prompt encoder. + + Args: + input_points (`torch.FloatTensor` of shape `(batch_size, point_batch_size, num_points_per_image, 2)`): + Optional input points for the prompt encoder. The padding of the point is automatically done by the + processor. `point_batch_size` refers to the number of masks that we want the model to predict per + point. The model will output `point_batch_size` times 3 masks in total. + input_labels (`torch.LongTensor` of shape `(batch_size, point_batch_size, num_points_per_image)`): + Optional input labels for the prompt encoder. The padding of the labels is automatically done by the + processor, or can be fed by the user. + input_boxes (`torch.FloatTensor` of shape `(batch_size, num_boxes_per_image, 4)`): + Optional input boxes for the prompt encoder. The padding of the boxes is automatically done by the + processor. users can also pass manually the input boxes. + input_masks (`torch.LongTensor` of shape `(batch_size, image_size, image_size)`): + Optional input masks for the prompt encoder. + """ + prompt_output = self.prompt_encoder( + input_points=input_points, + input_labels=input_labels, + input_boxes=input_boxes, + input_masks=input_masks, + ) + return prompt_output + + @merge_with_config_defaults + @capture_outputs + @auto_docstring + def forward( + self, + pixel_values: torch.FloatTensor | None = None, + input_points: torch.FloatTensor | None = None, + input_labels: torch.LongTensor | None = None, + input_boxes: torch.FloatTensor | None = None, + input_masks: torch.LongTensor | None = None, + image_embeddings: torch.FloatTensor | None = None, + multimask_output: bool = True, + attention_similarity: torch.FloatTensor | None = None, + target_embedding: torch.FloatTensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> SamImageSegmentationOutput: + r""" + input_points (`torch.FloatTensor` of shape `(batch_size, num_points, 2)`): + Input 2D spatial points, this is used by the prompt encoder to encode the prompt. Generally yields to much + better results. The points can be obtained by passing a list of list of list to the processor that will + create corresponding `torch` tensors of dimension 4. The first dimension is the image batch size, the + second dimension is the point batch size (i.e. how many segmentation masks do we want the model to predict + per input point), the third dimension is the number of points per segmentation mask (it is possible to pass + multiple points for a single mask), and the last dimension is the x (vertical) and y (horizontal) + coordinates of the point. If a different number of points is passed either for each image, or for each + mask, the processor will create "PAD" points that will correspond to the (0, 0) coordinate, and the + computation of the embedding will be skipped for these points using the labels. + input_labels (`torch.LongTensor` of shape `(batch_size, point_batch_size, num_points)`): + Input labels for the points, this is used by the prompt encoder to encode the prompt. According to the + official implementation, there are 3 types of labels + + - `1`: the point is a point that contains the object of interest + - `0`: the point is a point that does not contain the object of interest + - `-1`: the point corresponds to the background + + We added the label: + + - `-10`: the point is a padding point, thus should be ignored by the prompt encoder + + The padding labels should be automatically done by the processor. + input_boxes (`torch.FloatTensor` of shape `(batch_size, num_boxes, 4)`): + Input boxes for the points, this is used by the prompt encoder to encode the prompt. Generally yields to + much better generated masks. The boxes can be obtained by passing a list of list of list to the processor, + that will generate a `torch` tensor, with each dimension corresponding respectively to the image batch + size, the number of boxes per image and the coordinates of the top left and bottom right point of the box. + In the order (`x1`, `y1`, `x2`, `y2`): + + - `x1`: the x coordinate of the top left point of the input box + - `y1`: the y coordinate of the top left point of the input box + - `x2`: the x coordinate of the bottom right point of the input box + - `y2`: the y coordinate of the bottom right point of the input box + input_masks (`torch.FloatTensor` of shape `(batch_size, image_size, image_size)`): + SAM model also accepts segmentation masks as input. The mask will be embedded by the prompt encoder to + generate a corresponding embedding, that will be fed later on to the mask decoder. These masks needs to be + manually fed by the user, and they need to be of shape (`batch_size`, `image_size`, `image_size`). + image_embeddings (`torch.FloatTensor` of shape `(batch_size, output_channels, window_size, window_size)`): + Image embeddings, this is used by the mask decder to generate masks and iou scores. For more memory + efficient computation, users can first retrieve the image embeddings using the `get_image_embeddings` + method, and then feed them to the `forward` method instead of feeding the `pixel_values`. + multimask_output (`bool`, *optional*): + In the original implementation and paper, the model always outputs 3 masks per image (or per point / per + bounding box if relevant). However, it is possible to just output a single mask, that corresponds to the + "best" mask, by specifying `multimask_output=False`. + attention_similarity (`torch.FloatTensor`, *optional*): + Attention similarity tensor, to be provided to the mask decoder for target-guided attention in case the + model is used for personalization as introduced in [PerSAM](https://huggingface.co/papers/2305.03048). + target_embedding (`torch.FloatTensor`, *optional*): + Embedding of the target concept, to be provided to the mask decoder for target-semantic prompting in case + the model is used for personalization as introduced in [PerSAM](https://huggingface.co/papers/2305.03048). + + Example: + + ```python + >>> from PIL import Image + >>> import httpx + >>> from io import BytesIO + >>> from transformers import AutoModel, AutoProcessor + + >>> model = AutoModel.from_pretrained("facebook/sam-vit-base") + >>> processor = AutoProcessor.from_pretrained("facebook/sam-vit-base") + + >>> url = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/model_doc/sam-car.png" + >>> with httpx.stream("GET", url) as response: + ... raw_image = Image.open(BytesIO(response.read())).convert("RGB") + >>> input_points = [[[400, 650]]] # 2D location of a window on the car + >>> inputs = processor(images=raw_image, input_points=input_points, return_tensors="pt") + + >>> # Get segmentation mask + >>> outputs = model(**inputs) + + >>> # Postprocess masks + >>> masks = processor.post_process_masks( + ... outputs.pred_masks, inputs["original_sizes"], inputs["reshaped_input_sizes"] + ... ) + ``` + """ + if pixel_values is None and image_embeddings is None: + raise ValueError("Either pixel_values or image_embeddings must be provided.") + + if pixel_values is not None and image_embeddings is not None: + raise ValueError("Only one of pixel_values and image_embeddings can be provided.") + + if input_points is not None and len(input_points.shape) != 4: + raise ValueError( + "The input_points must be a 4D tensor. Of shape `batch_size`, `point_batch_size`, `nb_points_per_image`, `2`.", + f" got {input_points.shape}.", + ) + if input_boxes is not None and len(input_boxes.shape) != 3: + raise ValueError( + "The input_points must be a 3D tensor. Of shape `batch_size`, `nb_boxes`, `4`.", + f" got {input_boxes.shape}.", + ) + if input_points is not None and input_boxes is not None: + point_batch_size = input_points.shape[1] + box_batch_size = input_boxes.shape[1] + if point_batch_size != box_batch_size: + raise ValueError( + f"You should provide as many bounding boxes as input points per box. Got {point_batch_size} and {box_batch_size}." + ) + + image_positional_embeddings = self.get_image_wide_positional_embeddings() + # repeat with batch size + batch_size = pixel_values.shape[0] if pixel_values is not None else image_embeddings.shape[0] + image_positional_embeddings = image_positional_embeddings.repeat(batch_size, 1, 1, 1) + + vision_attentions = None + vision_hidden_states = None + + if pixel_values is not None: + vision_outputs: SamVisionEncoderOutput = self.vision_encoder(pixel_values, **kwargs) + image_embeddings = vision_outputs.last_hidden_state + vision_hidden_states = vision_outputs.hidden_states + vision_attentions = vision_outputs.attentions + + if input_points is not None and input_labels is None: + input_labels = torch.ones_like(input_points[:, :, :, 0], dtype=torch.int, device=input_points.device) + + if input_points is not None and image_embeddings.shape[0] != input_points.shape[0]: + raise ValueError( + "The batch size of the image embeddings and the input points must be the same. ", + f"Got {image_embeddings.shape[0]} and {input_points.shape[0]} respectively.", + " if you want to pass multiple points for the same image, make sure that you passed ", + " input_points of shape (batch_size, point_batch_size, num_points_per_image, 3) and ", + " input_labels of shape (batch_size, point_batch_size, num_points_per_image)", + ) + + sparse_embeddings, dense_embeddings = self.prompt_encoder( + input_points=input_points, + input_labels=input_labels, + input_boxes=input_boxes, + input_masks=input_masks, + ) + + low_res_masks, iou_predictions = self.mask_decoder( + image_embeddings=image_embeddings, + image_positional_embeddings=image_positional_embeddings, + sparse_prompt_embeddings=sparse_embeddings, + dense_prompt_embeddings=dense_embeddings, + multimask_output=multimask_output, + attention_similarity=attention_similarity, + target_embedding=target_embedding, + ) + + return SamImageSegmentationOutput( + iou_scores=iou_predictions, + pred_masks=low_res_masks, + vision_hidden_states=vision_hidden_states, + vision_attentions=vision_attentions, + ) + + +__all__ = ["SamVisionModel", "SamModel", "SamPreTrainedModel"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam/processing_sam.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam/processing_sam.py new file mode 100644 index 0000000000000000000000000000000000000000..017d30d7eef9e7a667b8563ca40c896610215c9b --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam/processing_sam.py @@ -0,0 +1,292 @@ +# Copyright 2023 The HuggingFace Inc. team. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +""" +Processor class for SAM. +""" + +from copy import deepcopy +from typing import Union + +import numpy as np + +from ...image_utils import ImageInput +from ...processing_utils import ImagesKwargs, ProcessingKwargs, ProcessorMixin +from ...tokenization_utils_base import BatchEncoding, PreTokenizedInput, TextInput +from ...utils import auto_docstring, is_torch_available + + +if is_torch_available(): + import torch + +NestedList = list[Union[float | int | None, "NestedList"]] + + +class SamImagesKwargs(ImagesKwargs, total=False): + """ + segmentation_maps (`ImageInput`, *optional*): + Ground truth segmentation maps to process alongside the input images. These maps are used for training + or evaluation purposes and are resized and normalized to match the processed image dimensions. + input_points (`NestedList`, *optional*): + Input points for prompt-based segmentation. Should be a nested list with structure + `[image_level, object_level, point_level, [x, y]]` where each point is specified as `[x, y]` coordinates + in the original image space. Points are normalized to the target image size before being passed to the model. + input_labels (`NestedList`, *optional*): + Labels for the input points, indicating whether each point is a foreground (1) or background (0) point. + Should be a nested list with structure `[image_level, object_level, point_level]`. Must have the same + structure as `input_points` (excluding the coordinate dimension). + input_boxes (`NestedList`, *optional*): + Bounding boxes for prompt-based segmentation. Should be a nested list with structure + `[image_level, box_level, [x1, y1, x2, y2]]` where each box is specified as `[x1, y1, x2, y2]` coordinates + in the original image space. Boxes are normalized to the target image size before being passed to the model. + point_pad_value (`int`, *optional*, defaults to `-10`): + The value used for padding input points when batching sequences of different lengths. This value marks + padded positions and is preserved during coordinate normalization to distinguish real points from padding. + mask_size (`dict[str, int]`, *optional*): + Dictionary specifying the target mask size with keys `"height"` and `"width"`. This determines the + resolution of the output segmentation masks generated by the model. + mask_pad_size (`dict[str, int]`, *optional*): + Dictionary specifying the padding size for masks with keys `"height"` and `"width"`. This is used when + batching masks of different sizes to ensure consistent dimensions. + """ + + segmentation_maps: ImageInput | None + input_points: "NestedList | torch.Tensor | None" + input_labels: "NestedList | int | torch.Tensor | None" + input_boxes: "NestedList | torch.Tensor | None" + point_pad_value: int | None + mask_size: dict[str, int] + mask_pad_size: dict[str, int] + + +class SamProcessorKwargs(ProcessingKwargs, total=False): + images_kwargs: SamImagesKwargs + _defaults = { + "images_kwargs": { + "point_pad_value": -10, + } + } + + +@auto_docstring +class SamProcessor(ProcessorMixin): + def __init__(self, image_processor): + super().__init__(image_processor) + self.target_size = self.image_processor.size["longest_edge"] + + @auto_docstring + def __call__( + self, + images: ImageInput | None = None, + text: TextInput | PreTokenizedInput | list[TextInput] | list[PreTokenizedInput] | None = None, + **kwargs, + ) -> BatchEncoding: + output_kwargs = self._merge_kwargs( + SamProcessorKwargs, + tokenizer_init_kwargs={}, + **kwargs, + ) + input_points = output_kwargs["images_kwargs"].pop("input_points", None) + input_labels = output_kwargs["images_kwargs"].pop("input_labels", None) + input_boxes = output_kwargs["images_kwargs"].pop("input_boxes", None) + point_pad_value = output_kwargs["images_kwargs"].pop("point_pad_value", None) + + encoding_image_processor = self.image_processor( + images, + **output_kwargs["images_kwargs"], + ) + + # pop arguments that are not used in the forward but used nevertheless + original_sizes = encoding_image_processor["original_sizes"] + + if hasattr(original_sizes, "numpy"): + original_sizes = original_sizes.numpy() + + input_points, input_labels, input_boxes = self._check_and_preprocess_points( + input_points=input_points, + input_labels=input_labels, + input_boxes=input_boxes, + ) + + encoding_image_processor = self._normalize_and_convert( + encoding_image_processor, + original_sizes, + input_points=input_points, + input_labels=input_labels, + input_boxes=input_boxes, + return_tensors=output_kwargs["images_kwargs"].get("return_tensors"), + point_pad_value=point_pad_value, + ) + + return encoding_image_processor + + def _normalize_and_convert( + self, + encoding_image_processor, + original_sizes, + input_points=None, + input_labels=None, + input_boxes=None, + return_tensors="pt", + point_pad_value=-10, + ): + if input_points is not None: + if len(original_sizes) != len(input_points): + input_points = [ + self._normalize_coordinates(self.target_size, point, original_sizes[0]) for point in input_points + ] + else: + input_points = [ + self._normalize_coordinates(self.target_size, point, original_size) + for point, original_size in zip(input_points, original_sizes) + ] + # check that all arrays have the same shape + if not all(point.shape == input_points[0].shape for point in input_points): + if input_labels is not None: + input_points, input_labels = self._pad_points_and_labels( + input_points, input_labels, point_pad_value + ) + + input_points = np.array(input_points) + + if input_labels is not None: + input_labels = np.array(input_labels) + + if input_boxes is not None: + if len(original_sizes) != len(input_boxes): + input_boxes = [ + self._normalize_coordinates(self.target_size, box, original_sizes[0], is_bounding_box=True) + for box in input_boxes + ] + else: + input_boxes = [ + self._normalize_coordinates(self.target_size, box, original_size, is_bounding_box=True) + for box, original_size in zip(input_boxes, original_sizes) + ] + input_boxes = np.array(input_boxes) + + if input_boxes is not None: + if return_tensors == "pt": + input_boxes = torch.from_numpy(input_boxes) + # boxes batch size of 1 by default + input_boxes = input_boxes.unsqueeze(1) if len(input_boxes.shape) != 3 else input_boxes + encoding_image_processor.update({"input_boxes": input_boxes}) + if input_points is not None: + if return_tensors == "pt": + input_points = torch.from_numpy(input_points) + # point batch size of 1 by default + input_points = input_points.unsqueeze(1) if len(input_points.shape) != 4 else input_points + encoding_image_processor.update({"input_points": input_points}) + if input_labels is not None: + if return_tensors == "pt": + input_labels = torch.from_numpy(input_labels) + # point batch size of 1 by default + input_labels = input_labels.unsqueeze(1) if len(input_labels.shape) != 3 else input_labels + encoding_image_processor.update({"input_labels": input_labels}) + + return encoding_image_processor + + def _pad_points_and_labels(self, input_points, input_labels, point_pad_value): + r""" + The method pads the 2D points and labels to the maximum number of points in the batch. + """ + expected_nb_points = max(point.shape[0] for point in input_points) + processed_input_points = [] + for i, point in enumerate(input_points): + if point.shape[0] != expected_nb_points: + point = np.concatenate( + [point, np.zeros((expected_nb_points - point.shape[0], 2)) + point_pad_value], axis=0 + ) + input_labels[i] = np.append(input_labels[i], [point_pad_value]) + processed_input_points.append(point) + input_points = processed_input_points + return input_points, input_labels + + def _normalize_coordinates( + self, target_size: int, coords: np.ndarray, original_size, is_bounding_box=False + ) -> np.ndarray: + """ + Expects a numpy array of length 2 in the final dimension. Requires the original image size in (H, W) format. + """ + old_h, old_w = original_size + new_h, new_w = self.image_processor._get_preprocess_shape(original_size, longest_edge=target_size) + coords = deepcopy(coords).astype(float) + + if is_bounding_box: + coords = coords.reshape(-1, 2, 2) + + coords[..., 0] = coords[..., 0] * (new_w / old_w) + coords[..., 1] = coords[..., 1] * (new_h / old_h) + + if is_bounding_box: + coords = coords.reshape(-1, 4) + + return coords + + def _check_and_preprocess_points( + self, + input_points=None, + input_labels=None, + input_boxes=None, + ): + r""" + Check and preprocesses the 2D points, labels and bounding boxes. It checks if the input is valid and if they + are, it converts the coordinates of the points and bounding boxes. If a user passes directly a `torch.Tensor`, + it is converted to a `numpy.ndarray` and then to a `list`. + """ + if input_points is not None: + if hasattr(input_points, "numpy"): + input_points = input_points.numpy().tolist() + + if not isinstance(input_points, list) or not isinstance(input_points[0], list): + raise ValueError("Input points must be a list of list of floating points.") + input_points = [np.array(input_point) for input_point in input_points] + else: + input_points = None + + if input_labels is not None: + if hasattr(input_labels, "numpy"): + input_labels = input_labels.numpy().tolist() + + if not isinstance(input_labels, list) or not isinstance(input_labels[0], list): + raise ValueError("Input labels must be a list of list integers.") + input_labels = [np.array(label) for label in input_labels] + else: + input_labels = None + + if input_boxes is not None: + if hasattr(input_boxes, "numpy"): + input_boxes = input_boxes.numpy().tolist() + + if ( + not isinstance(input_boxes, list) + or not isinstance(input_boxes[0], list) + or not isinstance(input_boxes[0][0], list) + ): + raise ValueError("Input boxes must be a list of list of list of floating points.") + input_boxes = [np.array(box).astype(np.float32) for box in input_boxes] + else: + input_boxes = None + + return input_points, input_labels, input_boxes + + @property + def model_input_names(self): + image_processor_input_names = self.image_processor.model_input_names + return list(image_processor_input_names + ["original_sizes", "reshaped_input_sizes"]) + + def post_process_masks(self, *args, **kwargs): + return self.image_processor.post_process_masks(*args, **kwargs) + + +__all__ = ["SamProcessor"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam2/__init__.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam2/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..38e6621b063af7a706186a1bf810e3f4709dc1b8 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam2/__init__.py @@ -0,0 +1,29 @@ +# Copyright 2024 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from typing import TYPE_CHECKING + +from ...utils import _LazyModule +from ...utils.import_utils import define_import_structure + + +if TYPE_CHECKING: + from .configuration_sam2 import * + from .image_processing_sam2_fast import * + from .modeling_sam2 import * + from .processing_sam2 import * +else: + import sys + + _file = globals()["__file__"] + sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__) diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam2/configuration_sam2.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam2/configuration_sam2.py new file mode 100644 index 0000000000000000000000000000000000000000..ee46446aa95b3d6df8d9d02f992be41e62f97f42 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam2/configuration_sam2.py @@ -0,0 +1,459 @@ +# Copyright 2025 The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""SAM2 model configuration""" + +from ...configuration_utils import PreTrainedConfig +from ...utils import logging +from ..auto import CONFIG_MAPPING, AutoConfig + + +logger = logging.get_logger(__name__) + + +class Sam2HieraDetConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`Sam2HieraDetModel`]. It is used to instantiate + a HieraDet model as defined in the original sam2 repo according to the specified arguments, defining the model architecture. + Instantiating a configuration defaults will yield a similar configuration to that of SAM 2.1 Hiera-tiny + [facebook/sam2.1-hiera-tiny](https://huggingface.co/facebook/sam2.1-hiera-tiny) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + hidden_size (`int`, *optional*, defaults to 96): + The hidden dimension of the image encoder. + num_attention_heads (`int`, *optional*, defaults to 1): + Number of attention heads for each attention layer in the Transformer encoder. + num_channels (`int`, *optional*, defaults to 3): + The number of channels in the image. + image_size (`list[int]`, *optional*, defaults to `[1024, 1024]`): + The size of the image. + patch_kernel_size (`list[int]`, *optional*, defaults to `[7, 7]`): + The kernel size of the patch. + patch_stride (`list[int]`, *optional*, defaults to `[4, 4]`): + The stride of the patch. + patch_padding (`list[int]`, *optional*, defaults to `[3, 3]`): + The padding of the patch. + query_stride (`list[int]`, *optional*, defaults to `[2, 2]`): + The downsample stride between stages. + window_positional_embedding_background_size (`list[int]`, *optional*, defaults to `[7, 7]`): + The window size per stage when not using global attention. + num_query_pool_stages (`int`, *optional*, defaults to 3): + The number of query pool stages. + blocks_per_stage (`list[int]`, *optional*, defaults to `[1, 2, 7, 2]`): + The number of blocks per stage. + embed_dim_per_stage (`list[int]`, *optional*, defaults to `[96, 192, 384, 768]`): + The embedding dimension per stage. + num_attention_heads_per_stage (`list[int]`, *optional*, defaults to `[1, 2, 4, 8]`): + The number of attention heads per stage. + window_size_per_stage (`list[int]`, *optional*, defaults to `[8, 4, 14, 7]`): + The window size per stage. + global_attention_blocks (`list[int]`, *optional*, defaults to `[5, 7, 9]`): + The blocks where global attention is used. + mlp_ratio (`float`, *optional*, defaults to 4.0): + The ratio of the MLP hidden dimension to the embedding dimension. + hidden_act (`str`, *optional*, defaults to `"gelu"`): + The non-linear activation function in the neck. + layer_norm_eps (`float`, *optional*, defaults to 1e-06): + The epsilon for the layer normalization. + initializer_range (`float`, *optional*, defaults to 0.02): + The standard deviation of the truncated_normal_initializer for initializing all weight matrices. + + """ + + base_config_key = "backbone_config" + model_type = "sam2_hiera_det_model" + + def __init__( + self, + hidden_size=96, + num_attention_heads=1, + num_channels=3, + image_size=None, + patch_kernel_size=None, + patch_stride=None, + patch_padding=None, + query_stride=None, + window_positional_embedding_background_size=None, + num_query_pool_stages=3, + blocks_per_stage=None, + embed_dim_per_stage=None, + num_attention_heads_per_stage=None, + window_size_per_stage=None, + global_attention_blocks=None, + mlp_ratio=4.0, + hidden_act="gelu", + layer_norm_eps=1e-6, + initializer_range=0.02, + **kwargs, + ): + super().__init__(**kwargs) + + image_size = image_size if image_size is not None else [1024, 1024] + patch_kernel_size = patch_kernel_size if patch_kernel_size is not None else [7, 7] + patch_stride = patch_stride if patch_stride is not None else [4, 4] + patch_padding = patch_padding if patch_padding is not None else [3, 3] + query_stride = query_stride if query_stride is not None else [2, 2] + window_positional_embedding_background_size = ( + window_positional_embedding_background_size + if window_positional_embedding_background_size is not None + else [7, 7] + ) + blocks_per_stage = blocks_per_stage if blocks_per_stage is not None else [1, 2, 7, 2] + embed_dim_per_stage = embed_dim_per_stage if embed_dim_per_stage is not None else [96, 192, 384, 768] + num_attention_heads_per_stage = ( + num_attention_heads_per_stage if num_attention_heads_per_stage is not None else [1, 2, 4, 8] + ) + window_size_per_stage = window_size_per_stage if window_size_per_stage is not None else [8, 4, 14, 7] + global_attention_blocks = global_attention_blocks if global_attention_blocks is not None else [5, 7, 9] + + self.hidden_size = hidden_size + self.num_attention_heads = num_attention_heads + self.num_channels = num_channels + self.image_size = image_size + self.patch_kernel_size = patch_kernel_size + self.patch_stride = patch_stride + self.patch_padding = patch_padding + self.query_stride = query_stride + self.window_positional_embedding_background_size = window_positional_embedding_background_size + self.num_query_pool_stages = num_query_pool_stages + self.blocks_per_stage = blocks_per_stage + self.embed_dim_per_stage = embed_dim_per_stage + self.num_attention_heads_per_stage = num_attention_heads_per_stage + self.window_size_per_stage = window_size_per_stage + self.global_attention_blocks = global_attention_blocks + self.mlp_ratio = mlp_ratio + self.hidden_act = hidden_act + self.layer_norm_eps = layer_norm_eps + self.initializer_range = initializer_range + + +class Sam2VisionConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`Sam2VisionModel`]. It is used to instantiate a SAM + vision encoder according to the specified arguments, defining the model architecture. Instantiating a configuration + defaults will yield a similar configuration to that of SAM 2.1 Hiera-tiny + [facebook/sam2.1-hiera-tiny](https://huggingface.co/facebook/sam2.1-hiera-tiny) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + backbone_config (`Union[dict, "PreTrainedConfig"]`, *optional*, defaults to `Sam2HieraDetConfig()`): + Configuration for the vision backbone. This is used to instantiate the backbone using + `AutoModel.from_config`. + backbone_channel_list (`List[int]`, *optional*, defaults to `[768, 384, 192, 96]`): + The list of channel dimensions for the backbone. + backbone_feature_sizes (`List[List[int]]`, *optional*, defaults to `[[256, 256], [128, 128], [64, 64]]`): + The spatial sizes of the feature maps from the backbone. + fpn_hidden_size (`int`, *optional*, defaults to 256): + The hidden dimension of the FPN. + fpn_kernel_size (`int`, *optional*, defaults to 1): + The kernel size for the convolutions in the neck. + fpn_stride (`int`, *optional*, defaults to 1): + The stride for the convolutions in the neck. + fpn_padding (`int`, *optional*, defaults to 0): + The padding for the convolutions in the neck. + fpn_top_down_levels (`List[int]`, *optional*, defaults to `[2, 3]`): + The levels for the top-down FPN connections. + num_feature_levels (`int`, *optional*, defaults to 3): + The number of feature levels from the FPN to use. + hidden_act (`str`, *optional*, defaults to `"gelu"`): + The non-linear activation function in the neck. + layer_norm_eps (`float`, *optional*, defaults to 1e-06): + The epsilon for the layer normalization. + initializer_range (`float`, *optional*, defaults to 0.02): + The standard deviation of the truncated_normal_initializer for initializing all weight matrices. + + """ + + base_config_key = "vision_config" + model_type = "sam2_vision_model" + sub_configs = { + "backbone_config": AutoConfig, + } + + def __init__( + self, + backbone_config=None, + backbone_channel_list=None, + backbone_feature_sizes=None, + fpn_hidden_size=256, + fpn_kernel_size=1, + fpn_stride=1, + fpn_padding=0, + fpn_top_down_levels=None, + num_feature_levels=3, + hidden_act="gelu", + layer_norm_eps=1e-6, + initializer_range=0.02, + **kwargs, + ): + backbone_channel_list = [768, 384, 192, 96] if backbone_channel_list is None else backbone_channel_list + backbone_feature_sizes = ( + [[256, 256], [128, 128], [64, 64]] if backbone_feature_sizes is None else backbone_feature_sizes + ) + fpn_top_down_levels = [2, 3] if fpn_top_down_levels is None else fpn_top_down_levels + + if isinstance(backbone_config, dict): + backbone_config["model_type"] = backbone_config.get("model_type", "sam2_hiera_det_model") + backbone_config = CONFIG_MAPPING[backbone_config["model_type"]](**backbone_config) + elif isinstance(backbone_config, Sam2HieraDetConfig): + pass + elif backbone_config is None: + backbone_config = Sam2HieraDetConfig() + + self.backbone_config = backbone_config + + # Neck + self.backbone_channel_list = backbone_channel_list + self.backbone_feature_sizes = backbone_feature_sizes + self.fpn_hidden_size = fpn_hidden_size + self.fpn_kernel_size = fpn_kernel_size + self.fpn_stride = fpn_stride + self.fpn_padding = fpn_padding + self.fpn_top_down_levels = fpn_top_down_levels + self.num_feature_levels = num_feature_levels + + self.hidden_act = hidden_act + self.layer_norm_eps = layer_norm_eps + self.initializer_range = initializer_range + super().__init__(**kwargs) + + +class Sam2PromptEncoderConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`Sam2PromptEncoder`]. The [`Sam2PromptEncoder`] + module is used to encode the input 2D points and bounding boxes. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + hidden_size (`int`, *optional*, defaults to 256): + Dimensionality of the hidden states. + image_size (`int`, *optional*, defaults to 1024): + The expected output resolution of the image. + patch_size (`int`, *optional*, defaults to 16): + The size (resolution) of each patch. + mask_input_channels (`int`, *optional*, defaults to 16): + The number of channels to be fed to the `MaskDecoder` module. + num_point_embeddings (`int`, *optional*, defaults to 4): + The number of point embeddings to be used. + hidden_act (`str`, *optional*, defaults to `"gelu"`): + The non-linear activation function in the encoder and pooler. + layer_norm_eps (`float`, *optional*, defaults to 1e-06): + The epsilon used by the layer normalization layers. + scale (`float`, *optional*, defaults to 1): + The scale factor for the prompt encoder. + """ + + base_config_key = "prompt_encoder_config" + + def __init__( + self, + hidden_size=256, + image_size=1024, + patch_size=16, + mask_input_channels=16, + num_point_embeddings=4, + hidden_act="gelu", + layer_norm_eps=1e-6, + scale=1, + **kwargs, + ): + super().__init__(**kwargs) + self.hidden_size = hidden_size + self.image_size = image_size + self.patch_size = patch_size + self.mask_input_channels = mask_input_channels + self.num_point_embeddings = num_point_embeddings + self.hidden_act = hidden_act + self.layer_norm_eps = layer_norm_eps + self.scale = scale + + +class Sam2MaskDecoderConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`Sam2MaskDecoder`]. It is used to instantiate a SAM2 + memory encoder according to the specified arguments, defining the model architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + hidden_size (`int`, *optional*, defaults to 256): + Dimensionality of the hidden states. + hidden_act (`str`, *optional*, defaults to `"gelu"`): + The non-linear activation function in the SAM2 mask decoder. + mlp_dim (`int`, *optional*, defaults to 2048): + The dimension of the MLP in the two-way transformer. + num_hidden_layers (`int`, *optional*, defaults to 2): + The number of hidden layers in the two-way transformer. + num_attention_heads (`int`, *optional*, defaults to 8): + The number of attention heads in the two-way transformer. + attention_downsample_rate (`int`, *optional*, defaults to 2): + The downsample rate for the attention layers. + num_multimask_outputs (`int`, *optional*, defaults to 3): + The number of multimask outputs. + iou_head_depth (`int`, *optional*, defaults to 3): + The depth of the IoU head. + iou_head_hidden_dim (`int`, *optional*, defaults to 256): + The hidden dimension of the IoU head. + dynamic_multimask_via_stability (`bool`, *optional*, defaults to `True`): + Whether to use dynamic multimask via stability. + dynamic_multimask_stability_delta (`float`, *optional*, defaults to 0.05): + The stability delta for the dynamic multimask. + dynamic_multimask_stability_thresh (`float`, *optional*, defaults to 0.98): + The stability threshold for the dynamic multimask. + + """ + + base_config_key = "mask_decoder_config" + + def __init__( + self, + hidden_size=256, + hidden_act="gelu", + mlp_dim=2048, + num_hidden_layers=2, + num_attention_heads=8, + attention_downsample_rate=2, + num_multimask_outputs=3, + iou_head_depth=3, + iou_head_hidden_dim=256, + dynamic_multimask_via_stability=True, + dynamic_multimask_stability_delta=0.05, + dynamic_multimask_stability_thresh=0.98, + **kwargs, + ): + super().__init__(**kwargs) + + self.hidden_size = hidden_size + self.num_multimask_outputs = num_multimask_outputs + self.hidden_act = hidden_act + self.iou_head_depth = iou_head_depth + self.iou_head_hidden_dim = iou_head_hidden_dim + self.dynamic_multimask_via_stability = dynamic_multimask_via_stability + self.dynamic_multimask_stability_delta = dynamic_multimask_stability_delta + self.dynamic_multimask_stability_thresh = dynamic_multimask_stability_thresh + + # TwoWayTransformer configuration + self.num_hidden_layers = num_hidden_layers + self.hidden_size = hidden_size + self.num_attention_heads = num_attention_heads + self.mlp_dim = mlp_dim + self.attention_downsample_rate = attention_downsample_rate + + +class Sam2Config(PreTrainedConfig): + r""" + [`Sam2Config`] is the configuration class to store the configuration of a [`Sam2Model`]. It is used to instantiate a + SAM2 model according to the specified arguments, defining the memory attention, memory encoder, and image encoder + configs. Instantiating a configuration defaults will yield a similar configuration to that of the SAM 2.1 Hiera-tiny + [facebook/sam2.1-hiera-tiny](https://huggingface.co/facebook/sam2.1-hiera-tiny) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + + + SAM2 checkpoints with `model_type="sam2_video"` are compatible with `Sam2Model` since the video variant weights + are a superset of the image-only model weights. You may see a warning about model type mismatch when loading + such checkpoints, which can be safely ignored in this case. + + + + Args: + vision_config (Union[`dict`, `Sam2VisionConfig`], *optional*): + Dictionary of configuration options used to initialize [`Sam2VisionConfig`]. + prompt_encoder_config (Union[`dict`, `Sam2PromptEncoderConfig`], *optional*): + Dictionary of configuration options used to initialize [`Sam2PromptEncoderConfig`]. + mask_decoder_config (Union[`dict`, `Sam2MaskDecoderConfig`], *optional*): + Dictionary of configuration options used to initialize [`Sam2MaskDecoderConfig`]. + initializer_range (`float`, *optional*, defaults to 0.02): + Standard deviation for parameter initialization. + + Example: + + ```python + >>> from transformers import ( + ... Sam2VisionConfig, + ... Sam2PromptEncoderConfig, + ... Sam2MaskDecoderConfig, + ... Sam2Model, + ... ) + + >>> # Initializing a Sam2Config with `"facebook/sam2.1_hiera_tiny"` style configuration + >>> configuration = Sam2Config() + + >>> # Initializing a Sam2Model (with random weights) from the `"facebook/sam2.1_hiera_tiny"` style configuration + >>> model = Sam2Model(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + + >>> # We can also initialize a Sam2Config from a Sam2VisionConfig, Sam2PromptEncoderConfig, and Sam2MaskDecoderConfig + + >>> # Initializing SAM2 vision encoder, memory attention, and memory encoder configurations + >>> vision_config = Sam2VisionConfig() + >>> prompt_encoder_config = Sam2PromptEncoderConfig() + >>> mask_decoder_config = Sam2MaskDecoderConfig() + + >>> config = Sam2Config(vision_config, prompt_encoder_config, mask_decoder_config) + ```""" + + model_type = "sam2" + sub_configs = { + "vision_config": AutoConfig, + "prompt_encoder_config": Sam2PromptEncoderConfig, + "mask_decoder_config": Sam2MaskDecoderConfig, + } + + def __init__( + self, + vision_config=None, + prompt_encoder_config=None, + mask_decoder_config=None, + initializer_range=0.02, + **kwargs, + ): + vision_config = vision_config if vision_config is not None else {} + prompt_encoder_config = prompt_encoder_config if prompt_encoder_config is not None else {} + mask_decoder_config = mask_decoder_config if mask_decoder_config is not None else {} + + if isinstance(vision_config, dict): + vision_config["model_type"] = vision_config.get("model_type", "sam2_vision_model") + vision_config = CONFIG_MAPPING[vision_config["model_type"]](**vision_config) + if isinstance(prompt_encoder_config, Sam2PromptEncoderConfig): + prompt_encoder_config = prompt_encoder_config.to_dict() + if isinstance(mask_decoder_config, Sam2MaskDecoderConfig): + mask_decoder_config = mask_decoder_config.to_dict() + + self.vision_config = vision_config + self.prompt_encoder_config = Sam2PromptEncoderConfig(**prompt_encoder_config) + self.mask_decoder_config = Sam2MaskDecoderConfig(**mask_decoder_config) + + self.initializer_range = initializer_range + super().__init__(**kwargs) + + +__all__ = [ + "Sam2Config", + "Sam2HieraDetConfig", + "Sam2VisionConfig", + "Sam2PromptEncoderConfig", + "Sam2MaskDecoderConfig", +] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam2/image_processing_sam2_fast.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam2/image_processing_sam2_fast.py new file mode 100644 index 0000000000000000000000000000000000000000..6b5c4edb17917e6ce153434f67385582ab62b60a --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam2/image_processing_sam2_fast.py @@ -0,0 +1,724 @@ +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# This file was automatically generated from src/transformers/models/sam2/modular_sam2.py. +# Do NOT edit this file manually as any edits will be overwritten by the generation of +# the file from the modular. If any change should be done, please apply the change to the +# modular_sam2.py file directly. One of our CI enforces this. +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# Copyright 2025 The Meta AI Authors and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +import math +from copy import deepcopy +from itertools import product +from typing import Any, Optional, Union + +import numpy as np +import torch +import torch.nn.functional as F +from torchvision.ops.boxes import batched_nms + +from ...image_processing_utils import BatchFeature, get_size_dict +from ...image_processing_utils_fast import BaseImageProcessorFast +from ...image_utils import ( + IMAGENET_DEFAULT_MEAN, + IMAGENET_DEFAULT_STD, + ChannelDimension, + ImageInput, + PILImageResampling, + SizeDict, + pil_torch_interpolation_mapping, +) +from ...processing_utils import ImagesKwargs, Unpack +from ...utils import TensorType, auto_docstring + + +class Sam2FastImageProcessorKwargs(ImagesKwargs, total=False): + r""" + mask_size (`dict[str, int]`, *optional*): + The size `{"height": int, "width": int}` to resize the segmentation maps to. + """ + + mask_size: dict[str, int] + + +def _compute_stability_score(masks: "torch.Tensor", mask_threshold: float, stability_score_offset: int): + # One mask is always contained inside the other. + # Save memory by preventing unnecessary cast to torch.int64 + intersections = ( + (masks > (mask_threshold + stability_score_offset)).sum(-1, dtype=torch.int16).sum(-1, dtype=torch.int32) + ) + unions = (masks > (mask_threshold - stability_score_offset)).sum(-1, dtype=torch.int16).sum(-1, dtype=torch.int32) + stability_scores = intersections / unions + return stability_scores + + +def _mask_to_rle(input_mask: "torch.Tensor"): + """ + Encodes masks the run-length encoding (RLE), in the format expected by pycoco tools. + """ + # Put in fortran order and flatten height and width + batch_size, height, width = input_mask.shape + input_mask = input_mask.permute(0, 2, 1).flatten(1) + + # Compute change indices + diff = input_mask[:, 1:] ^ input_mask[:, :-1] + change_indices = diff.nonzero() + + # Encode run length + out = [] + for i in range(batch_size): + cur_idxs = change_indices[change_indices[:, 0] == i, 1] + 1 + if len(cur_idxs) == 0: + # No changes => either all 0 or all 1 + # If the entire mask is 0, RLE is [height*width] or if the entire mask is 1, RLE is [0, height*width]. + if input_mask[i, 0] == 0: + out.append({"size": [height, width], "counts": [height * width]}) + else: + out.append({"size": [height, width], "counts": [0, height * width]}) + continue + btw_idxs = cur_idxs[1:] - cur_idxs[:-1] + counts = [] if input_mask[i, 0] == 0 else [0] + counts += [cur_idxs[0].item()] + btw_idxs.tolist() + [height * width - cur_idxs[-1].item()] + out.append({"size": [height, width], "counts": counts}) + return out + + +def _batched_mask_to_box(masks: "torch.Tensor"): + """ + Computes the bounding boxes around the given input masks. The bounding boxes are in the XYXY format which + corresponds the following required indices: + - LEFT: left hand side of the bounding box + - TOP: top of the bounding box + - RIGHT: right of the bounding box + - BOTTOM: bottom of the bounding box + + Return [0,0,0,0] for an empty mask. For input shape channel_1 x channel_2 x ... x height x width, the output shape + is channel_1 x channel_2 x ... x 4. + + Args: + - masks (`torch.Tensor` of shape `(batch, nb_mask, height, width)`) + """ + # torch.max below raises an error on empty inputs, just skip in this case + + if torch.numel(masks) == 0: + return torch.zeros(*masks.shape[:-2], 4, device=masks.device) + + # Normalize shape to Cxheightxwidth + shape = masks.shape + height, width = shape[-2:] + + # Get top and bottom edges + in_height, _ = torch.max(masks, dim=-1) + in_height_coords = in_height * torch.arange(height, device=in_height.device)[None, :] + bottom_edges, _ = torch.max(in_height_coords, dim=-1) + in_height_coords = in_height_coords + height * (~in_height) + top_edges, _ = torch.min(in_height_coords, dim=-1) + + # Get left and right edges + in_width, _ = torch.max(masks, dim=-2) + in_width_coords = in_width * torch.arange(width, device=in_width.device)[None, :] + right_edges, _ = torch.max(in_width_coords, dim=-1) + in_width_coords = in_width_coords + width * (~in_width) + left_edges, _ = torch.min(in_width_coords, dim=-1) + + # If the mask is empty the right edge will be to the left of the left edge. + # Replace these boxes with [0, 0, 0, 0] + empty_filter = (right_edges < left_edges) | (bottom_edges < top_edges) + out = torch.stack([left_edges, top_edges, right_edges, bottom_edges], dim=-1) + out = out * (~empty_filter).unsqueeze(-1) + + # Return to original shape + out = out.reshape(*shape[:-2], 4) + return out + + +def _is_box_near_crop_edge(boxes, crop_box, orig_box, atol=20.0): + """Filter masks at the edge of a crop, but not at the edge of the original image.""" + crop_box_torch = torch.as_tensor(crop_box, dtype=torch.float, device=boxes.device) + orig_box_torch = torch.as_tensor(orig_box, dtype=torch.float, device=boxes.device) + + left, top, _, _ = crop_box + offset = torch.tensor([[left, top, left, top]], device=boxes.device) + # Check if boxes has a channel dimension + if len(boxes.shape) == 3: + offset = offset.unsqueeze(1) + boxes = (boxes + offset).float() + + near_crop_edge = torch.isclose(boxes, crop_box_torch[None, :], atol=atol, rtol=0) + near_image_edge = torch.isclose(boxes, orig_box_torch[None, :], atol=atol, rtol=0) + near_crop_edge = torch.logical_and(near_crop_edge, ~near_image_edge) + return torch.any(near_crop_edge, dim=1) + + +def _pad_masks(masks, crop_box: list[int], orig_height: int, orig_width: int): + left, top, right, bottom = crop_box + if left == 0 and top == 0 and right == orig_width and bottom == orig_height: + return masks + # Coordinate transform masks + pad_x, pad_y = orig_width - (right - left), orig_height - (bottom - top) + pad = (left, pad_x - left, top, pad_y - top) + return torch.nn.functional.pad(masks, pad, value=0) + + +def _generate_crop_boxes( + image, + target_size: int, # Is it tuple here? + crop_n_layers: int = 0, + overlap_ratio: float = 512 / 1500, + points_per_crop: int | None = 32, + crop_n_points_downscale_factor: list[int] | None = 1, +) -> tuple[list[list[int]], list[int]]: + """ + Generates a list of crop boxes of different sizes. Each layer has (2**i)**2 boxes for the ith layer. + + Args: + image (Union[`numpy.ndarray`, `PIL.Image`, `torch.Tensor`]): + Image to generate crops for. + target_size (`int`): + Size of the smallest crop. + crop_n_layers (`int`, *optional*): + If `crops_n_layers>0`, mask prediction will be run again on crops of the image. Sets the number of layers + to run, where each layer has 2**i_layer number of image crops. + overlap_ratio (`int`, *optional*): + Sets the degree to which crops overlap. In the first crop layer, crops will overlap by this fraction of the + image length. Later layers with more crops scale down this overlap. + points_per_crop (`int`, *optional*): + Number of points to sam2ple per crop. + crop_n_points_downscale_factor (`int`, *optional*): + The number of points-per-side sam2pled in layer n is scaled down by crop_n_points_downscale_factor**n. + input_data_format (`str` or `ChannelDimension`, *optional*): + The channel dimension format of the input image. If not provided, it will be inferred. + """ + + if isinstance(image, list): + raise ValueError("Only one image is allowed for crop generation.") + original_size = image.shape[-2:] + + points_grid = [] + for i in range(crop_n_layers + 1): + n_points = int(points_per_crop / (crop_n_points_downscale_factor**i)) + points_grid.append(_build_point_grid(n_points)) + + crop_boxes, layer_idxs = _generate_per_layer_crops(crop_n_layers, overlap_ratio, original_size) + + cropped_images, point_grid_per_crop = _generate_crop_images( + crop_boxes, image, points_grid, layer_idxs, target_size, original_size + ) + crop_boxes = torch.tensor(crop_boxes) + crop_boxes = crop_boxes.float() + points_per_crop = torch.stack(point_grid_per_crop) + points_per_crop = points_per_crop.unsqueeze(0).permute(0, 2, 1, 3) + cropped_images = torch.stack(cropped_images) + + input_labels = torch.ones_like(points_per_crop[:, :, :, 0], dtype=torch.int64) + + return crop_boxes, points_per_crop, cropped_images, input_labels + + +def _generate_per_layer_crops(crop_n_layers, overlap_ratio, original_size): + """ + Generates 2 ** (layers idx + 1) crops for each crop_n_layers. Crops are in the XYWH format : The XYWH format + consists of the following required indices: + - X: X coordinate of the top left of the bounding box + - Y: Y coordinate of the top left of the bounding box + - W: width of the bounding box + - H: height of the bounding box + """ + crop_boxes, layer_idxs = [], [] + im_height, im_width = original_size + short_side = min(im_height, im_width) + + # Original image + crop_boxes.append([0, 0, im_width, im_height]) + layer_idxs.append(0) + for i_layer in range(crop_n_layers): + n_crops_per_side = 2 ** (i_layer + 1) + overlap = int(overlap_ratio * short_side * (2 / n_crops_per_side)) + + crop_width = int(math.ceil((overlap * (n_crops_per_side - 1) + im_width) / n_crops_per_side)) + crop_height = int(math.ceil((overlap * (n_crops_per_side - 1) + im_height) / n_crops_per_side)) + + crop_box_x0 = [int((crop_width - overlap) * i) for i in range(n_crops_per_side)] + crop_box_y0 = [int((crop_height - overlap) * i) for i in range(n_crops_per_side)] + + for left, top in product(crop_box_x0, crop_box_y0): + box = [left, top, min(left + crop_width, im_width), min(top + crop_height, im_height)] + crop_boxes.append(box) + layer_idxs.append(i_layer + 1) + + return crop_boxes, layer_idxs + + +def _build_point_grid(n_per_side: int) -> torch.Tensor: + """Generates a 2D grid of points evenly spaced in [0,1]x[0,1].""" + offset = 1 / (2 * n_per_side) + points_one_side = torch.linspace(offset, 1 - offset, n_per_side) + points_x = torch.tile(points_one_side[None, :], (n_per_side, 1)) + points_y = torch.tile(points_one_side[:, None], (1, n_per_side)) + points = torch.stack([points_x, points_y], dim=-1).reshape(-1, 2) + return points + + +def _generate_crop_images( + crop_boxes, image, points_grid, layer_idxs, target_size, original_size, input_data_format=None +): + """ + Takes as an input bounding boxes that are used to crop the image. Based in the crops, the corresponding points are + also passed. + """ + cropped_images = [] + total_points_per_crop = [] + for i, crop_box in enumerate(crop_boxes): + left, top, right, bottom = crop_box + cropped_im = image[:, top:bottom, left:right] + + cropped_images.append(cropped_im) + + cropped_im_size = cropped_im.shape[-2:] + points_scale = torch.tensor(cropped_im_size).flip(dims=(0,)).unsqueeze(0) + + points = points_grid[layer_idxs[i]] * points_scale + normalized_points = _normalize_coordinates(target_size, points, original_size) + total_points_per_crop.append(normalized_points) + + return cropped_images, total_points_per_crop + + +def _normalize_coordinates( + target_size: int, coords: torch.Tensor, original_size: tuple[int, int], is_bounding_box=False +) -> torch.Tensor: + """ + Expects a numpy array of length 2 in the final dimension. Requires the original image size in (height, width) + format. + """ + old_height, old_width = original_size + + scale = target_size * 1.0 / max(old_height, old_width) + new_height, new_width = old_height * scale, old_width * scale + new_width = int(new_width + 0.5) + new_height = int(new_height + 0.5) + + coords = deepcopy(coords).float() + + if is_bounding_box: + coords = coords.reshape(-1, 2, 2) + + coords[..., 0] = coords[..., 0] * (new_width / old_width) + coords[..., 1] = coords[..., 1] * (new_height / old_height) + + if is_bounding_box: + coords = coords.reshape(-1, 4) + + return coords + + +def _rle_to_mask(rle: dict[str, Any]) -> torch.Tensor: + """Compute a binary mask from an uncompressed RLE.""" + height, width = rle["size"] + mask = torch.empty(height * width, dtype=bool) + idx = 0 + parity = False + for count in rle["counts"]: + mask[idx : idx + count] = parity + idx += count + parity = not parity + mask = mask.reshape(width, height) + return mask.transpose(0, 1) # Reshape to original shape + + +def _post_process_for_mask_generation(rle_masks, iou_scores, mask_boxes, amg_crops_nms_thresh=0.7): + """ + Perform NMS (Non Maximum Suppression) on the outputs. + + Args: + rle_masks (`torch.Tensor`): + binary masks in the RLE format + iou_scores (`torch.Tensor` of shape (nb_masks, 1)): + iou_scores predicted by the model + mask_boxes (`torch.Tensor`): + The bounding boxes corresponding to segmentation masks + amg_crops_nms_thresh (`float`, *optional*, defaults to 0.7): + NMS threshold. + """ + keep_by_nms = batched_nms( + boxes=mask_boxes.float(), + scores=iou_scores, + idxs=torch.zeros(mask_boxes.shape[0]), + iou_threshold=amg_crops_nms_thresh, + ) + + iou_scores = iou_scores[keep_by_nms] + rle_masks = [rle_masks[i] for i in keep_by_nms] + mask_boxes = mask_boxes[keep_by_nms] + masks = [_rle_to_mask(rle) for rle in rle_masks] + + return masks, iou_scores, rle_masks, mask_boxes + + +@auto_docstring +class Sam2ImageProcessorFast(BaseImageProcessorFast): + resample = PILImageResampling.BILINEAR + image_mean = IMAGENET_DEFAULT_MEAN + image_std = IMAGENET_DEFAULT_STD + size = {"height": 1024, "width": 1024} + mask_size = {"height": 256, "width": 256} + do_resize = True + do_rescale = True + do_normalize = True + do_convert_rgb = True + + valid_kwargs = Sam2FastImageProcessorKwargs + + # modular artefacts + do_pad = None + pad_size = None + mask_pad_size = None + + def __init__(self, **kwargs: Unpack[Sam2FastImageProcessorKwargs]): + super().__init__(**kwargs) + + def _further_process_kwargs( + self, + size: SizeDict | None = None, + mask_size: SizeDict | None = None, + default_to_square: bool | None = None, + image_mean: float | list[float] | None = None, + image_std: float | list[float] | None = None, + data_format: ChannelDimension | None = None, + **kwargs, + ) -> dict: + """ + Update kwargs that need further processing before being validated + Can be overridden by subclasses to customize the processing of kwargs. + """ + if kwargs is None: + kwargs = {} + if size is not None: + size = SizeDict(**get_size_dict(size=size, default_to_square=default_to_square)) + if mask_size is not None: + mask_size = SizeDict(**get_size_dict(mask_size, param_name="mask_size")) + if isinstance(image_mean, list): + image_mean = tuple(image_mean) + if isinstance(image_std, list): + image_std = tuple(image_std) + if data_format is None: + data_format = ChannelDimension.FIRST + + kwargs["size"] = size + kwargs["mask_size"] = mask_size + kwargs["image_mean"] = image_mean + kwargs["image_std"] = image_std + kwargs["data_format"] = data_format + + # torch resize uses interpolation instead of resample + # Check if resample is an int before checking if it's an instance of PILImageResampling + # because if pillow < 9.1.0, resample is an int and PILImageResampling is a module. + # Checking PILImageResampling will fail with error `TypeError: isinstance() arg 2 must be a type or tuple of types`. + resample = kwargs.pop("resample") + kwargs["interpolation"] = ( + pil_torch_interpolation_mapping[resample] if isinstance(resample, (PILImageResampling, int)) else resample + ) + + return kwargs + + @auto_docstring + def preprocess( + self, + images: ImageInput, + segmentation_maps: ImageInput | None = None, + **kwargs: Unpack[Sam2FastImageProcessorKwargs], + ) -> BatchFeature: + r""" + segmentation_maps (`ImageInput`, *optional*): + The segmentation maps to preprocess. + """ + return super().preprocess(images, segmentation_maps, **kwargs) + + def _preprocess_image_like_inputs( + self, + images: ImageInput, + segmentation_maps: ImageInput | None, + do_convert_rgb: bool, + input_data_format: ChannelDimension, + device: Union[str, "torch.device"] | None = None, + **kwargs: Unpack[Sam2FastImageProcessorKwargs], + ) -> BatchFeature: + """ + Preprocess image-like inputs. + """ + images = self._prepare_image_like_inputs( + images=images, do_convert_rgb=do_convert_rgb, input_data_format=input_data_format, device=device + ) + original_sizes = [image.shape[-2:] for image in images] + images_kwargs = kwargs.copy() + pixel_values = self._preprocess(images, **images_kwargs) + data = { + "pixel_values": pixel_values, + "original_sizes": original_sizes, + } + + if segmentation_maps is not None: + processed_segmentation_maps = self._prepare_image_like_inputs( + images=segmentation_maps, + expected_ndims=2, + do_convert_rgb=False, + input_data_format=ChannelDimension.FIRST, + ) + + segmentation_maps_kwargs = kwargs.copy() + segmentation_maps_kwargs.update( + { + "do_normalize": False, + "do_rescale": False, + "interpolation": pil_torch_interpolation_mapping[PILImageResampling.NEAREST], + "size": segmentation_maps_kwargs.pop("mask_size"), + } + ) + processed_segmentation_maps = self._preprocess( + images=processed_segmentation_maps, **segmentation_maps_kwargs + ) + data["labels"] = processed_segmentation_maps.squeeze(1).to(torch.int64) + + return BatchFeature(data=data, tensor_type=kwargs["return_tensors"]) + + def _preprocess( + self, + images: list["torch.Tensor"], + return_tensors: str | TensorType | None, + **kwargs, + ) -> "torch.Tensor": + return super()._preprocess(images, return_tensors=return_tensors, **kwargs).pixel_values + + def generate_crop_boxes( + self, + image: "torch.Tensor", + target_size, + crop_n_layers: int = 0, + overlap_ratio: float = 512 / 1500, + points_per_crop: int | None = 32, + crop_n_points_downscale_factor: list[int] | None = 1, + device: Optional["torch.device"] = None, + ): + """ + Generates a list of crop boxes of different sizes. Each layer has (2**i)**2 boxes for the ith layer. + + Args: + image (`torch.Tensor`): + Input original image + target_size (`int`): + Target size of the resized image + crop_n_layers (`int`, *optional*, defaults to 0): + If >0, mask prediction will be run again on crops of the image. Sets the number of layers to run, where + each layer has 2**i_layer number of image crops. + overlap_ratio (`float`, *optional*, defaults to 512/1500): + Sets the degree to which crops overlap. In the first crop layer, crops will overlap by this fraction of + the image length. Later layers with more crops scale down this overlap. + points_per_crop (`int`, *optional*, defaults to 32): + Number of points to sam2ple from each crop. + crop_n_points_downscale_factor (`list[int]`, *optional*, defaults to 1): + The number of points-per-side sam2pled in layer n is scaled down by crop_n_points_downscale_factor**n. + device (`torch.device`, *optional*, defaults to None): + Device to use for the computation. If None, cpu will be used. + input_data_format (`str` or `ChannelDimension`, *optional*): + The channel dimension format of the input image. If not provided, it will be inferred. + return_tensors (`str`, *optional*, defaults to `pt`): + If `pt`, returns `torch.Tensor`. + """ + image = self._process_image(image) + crop_boxes, points_per_crop, cropped_images, input_labels = _generate_crop_boxes( + image, + target_size, + crop_n_layers, + overlap_ratio, + points_per_crop, + crop_n_points_downscale_factor, + ) + if device is None: + device = torch.device("cpu") + crop_boxes = crop_boxes.to(device) + points_per_crop = points_per_crop.to(device) + # cropped_images stays as torch.Tensor + input_labels = input_labels.to(device) + + return crop_boxes, points_per_crop, cropped_images, input_labels + + def filter_masks( + self, + masks, + iou_scores, + original_size, + cropped_box_image, + pred_iou_thresh=0.88, + stability_score_thresh=0.95, + mask_threshold=0, + stability_score_offset=1, + ): + """ + Filters the predicted masks by selecting only the ones that meets several criteria. The first criterion being + that the iou scores needs to be greater than `pred_iou_thresh`. The second criterion is that the stability + score needs to be greater than `stability_score_thresh`. The method also converts the predicted masks to + bounding boxes and pad the predicted masks if necessary. + + Args: + masks (`torch.Tensor`): + Input masks. + iou_scores (`torch.Tensor`): + List of IoU scores. + original_size (`tuple[int,int]`): + Size of the original image. + cropped_box_image (`torch.Tensor`): + The cropped image. + pred_iou_thresh (`float`, *optional*, defaults to 0.88): + The threshold for the iou scores. + stability_score_thresh (`float`, *optional*, defaults to 0.95): + The threshold for the stability score. + mask_threshold (`float`, *optional*, defaults to 0): + The threshold for the predicted masks. + stability_score_offset (`float`, *optional*, defaults to 1): + The offset for the stability score used in the `_compute_stability_score` method. + + """ + original_height, original_width = original_size + iou_scores = iou_scores.flatten(0, 1) + masks = masks.flatten(0, 1) + + if masks.shape[0] != iou_scores.shape[0]: + raise ValueError("masks and iou_scores must have the sam2e batch size.") + + if masks.device != iou_scores.device: + iou_scores = iou_scores.to(masks.device) + + batch_size = masks.shape[0] + + keep_mask = torch.ones(batch_size, dtype=torch.bool, device=masks.device) + + if pred_iou_thresh > 0.0: + keep_mask = keep_mask & (iou_scores > pred_iou_thresh) + + # compute stability score + if stability_score_thresh > 0.0: + stability_scores = _compute_stability_score(masks, mask_threshold, stability_score_offset) + keep_mask = keep_mask & (stability_scores > stability_score_thresh) + + scores = iou_scores[keep_mask] + masks = masks[keep_mask] + + # binarize masks + masks = masks > mask_threshold + converted_boxes = _batched_mask_to_box(masks) + + keep_mask = ~_is_box_near_crop_edge( + converted_boxes, cropped_box_image, [0, 0, original_width, original_height] + ) + + scores = scores[keep_mask] + masks = masks[keep_mask] + converted_boxes = converted_boxes[keep_mask] + + masks = _pad_masks(masks, cropped_box_image, original_height, original_width) + # conversion to rle is necessary to run non-maximum suppression + masks = _mask_to_rle(masks) + + return masks, scores, converted_boxes + + def post_process_masks( + self, + masks, + original_sizes, + mask_threshold=0.0, + binarize=True, + max_hole_area=0.0, + max_sprinkle_area=0.0, + apply_non_overlapping_constraints=False, + **kwargs, + ): + """ + Remove padding and upscale masks to the original image size. + + Args: + masks (`Union[torch.Tensor, List[torch.Tensor], np.ndarray, List[np.ndarray]]`): + Batched masks from the mask_decoder in (batch_size, num_channels, height, width) format. + original_sizes (`Union[torch.Tensor, List[Tuple[int,int]]]`): + The original sizes of each image before it was resized to the model's expected input shape, in (height, + width) format. + mask_threshold (`float`, *optional*, defaults to 0.0): + Threshold for binarization and post-processing operations. + binarize (`bool`, *optional*, defaults to `True`): + Whether to binarize the masks. + max_hole_area (`float`, *optional*, defaults to 0.0): + The maximum area of a hole to fill. + max_sprinkle_area (`float`, *optional*, defaults to 0.0): + The maximum area of a sprinkle to fill. + apply_non_overlapping_constraints (`bool`, *optional*, defaults to `False`): + Whether to apply non-overlapping constraints to the masks. + + Returns: + (`torch.Tensor`): Batched masks in batch_size, num_channels, height, width) format, where (height, width) + is given by original_size. + """ + if isinstance(original_sizes, (torch.Tensor, np.ndarray)): + original_sizes = original_sizes.tolist() + # TODO: add connected components kernel for postprocessing + output_masks = [] + for i, original_size in enumerate(original_sizes): + if isinstance(masks[i], np.ndarray): + masks[i] = torch.from_numpy(masks[i]) + elif not isinstance(masks[i], torch.Tensor): + raise TypeError("Input masks should be a list of `torch.tensors` or a list of `np.ndarray`") + interpolated_mask = F.interpolate(masks[i], original_size, mode="bilinear", align_corners=False) + if apply_non_overlapping_constraints: + interpolated_mask = self._apply_non_overlapping_constraints(interpolated_mask) + if binarize: + interpolated_mask = interpolated_mask > mask_threshold + output_masks.append(interpolated_mask) + + return output_masks + + def post_process_for_mask_generation(self, all_masks, all_scores, all_boxes, crops_nms_thresh): + """ + Post processes mask that are generated by calling the Non Maximum Suppression algorithm on the predicted masks. + + Args: + all_masks (`torch.Tensor`): + List of all predicted segmentation masks + all_scores (`torch.Tensor`): + List of all predicted iou scores + all_boxes (`torch.Tensor`): + List of all bounding boxes of the predicted masks + crops_nms_thresh (`float`): + Threshold for NMS (Non Maximum Suppression) algorithm. + """ + return _post_process_for_mask_generation(all_masks, all_scores, all_boxes, crops_nms_thresh) + + def _apply_non_overlapping_constraints(self, pred_masks: torch.Tensor) -> torch.Tensor: + """ + Apply non-overlapping constraints to the object scores in pred_masks. Here we + keep only the highest scoring object at each spatial location in pred_masks. + """ + batch_size = pred_masks.size(0) + if batch_size == 1: + return pred_masks + + device = pred_masks.device + # "max_obj_inds": object index of the object with the highest score at each location + max_obj_inds = torch.argmax(pred_masks, dim=0, keepdim=True) + # "batch_obj_inds": object index of each object slice (along dim 0) in `pred_masks` + batch_obj_inds = torch.arange(batch_size, device=device)[:, None, None, None] + keep = max_obj_inds == batch_obj_inds + # suppress overlapping regions' scores below -10.0 so that the foreground regions + # don't overlap (here sigmoid(-10.0)=4.5398e-05) + pred_masks = torch.where(keep, pred_masks, torch.clamp(pred_masks, max=-10.0)) + return pred_masks + + +__all__ = ["Sam2ImageProcessorFast"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam2/modeling_sam2.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam2/modeling_sam2.py new file mode 100644 index 0000000000000000000000000000000000000000..cf598e4c49d98e5af41d8beaa50fefd5b606cca1 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam2/modeling_sam2.py @@ -0,0 +1,1608 @@ +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# This file was automatically generated from src/transformers/models/sam2/modular_sam2.py. +# Do NOT edit this file manually as any edits will be overwritten by the generation of +# the file from the modular. If any change should be done, please apply the change to the +# modular_sam2.py file directly. One of our CI enforces this. +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# Copyright 2025 The Meta AI Authors and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import math +from collections.abc import Callable +from dataclasses import dataclass + +import numpy as np +import torch +import torch.nn as nn +import torch.nn.functional as F +from torch import Tensor + +from ... import initialization as init +from ...activations import ACT2FN +from ...modeling_layers import GradientCheckpointingLayer +from ...modeling_outputs import BaseModelOutput, BaseModelOutputWithPooling +from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel +from ...processing_utils import Unpack +from ...pytorch_utils import compile_compatible_method_lru_cache +from ...utils import ( + ModelOutput, + auto_docstring, + can_return_tuple, + logging, +) +from ...utils.generic import TransformersKwargs, is_flash_attention_requested, merge_with_config_defaults +from ...utils.output_capturing import OutputRecorder, capture_outputs +from ..auto import AutoModel +from .configuration_sam2 import ( + Sam2Config, + Sam2HieraDetConfig, + Sam2MaskDecoderConfig, + Sam2PromptEncoderConfig, + Sam2VisionConfig, +) + + +logger = logging.get_logger(__name__) + + +@dataclass +@auto_docstring(custom_intro="Base class for the vision encoder's outputs.") +class Sam2VisionEncoderOutput(BaseModelOutputWithPooling): + r""" + last_hidden_state (`torch.FloatTensor` of shape `(batch_size, height, width, hidden_size)`): + Sequence of hidden-states at the output of the last layer of the model. + hidden_states (`tuple(torch.FloatTensor)`, *optional*, returned when `output_hidden_states=True` is passed or when `config.output_hidden_states=True`): + Tuple of `torch.FloatTensor` (one for the output of the embeddings, if the model has an embedding layer, + + one for the output of each stage) of shape `(batch_size, height, width, hidden_size)`. Hidden-states of the + model at the output of each stage. + attentions (`tuple(torch.FloatTensor)`, *optional*, returned when `output_attentions=True` is passed or when `config.output_attentions=True`): + Tuple of `torch.FloatTensor` (one for each layer) of shape `(batch_size, num_heads, sequence_length, + sequence_length)`. Attentions weights after the attention softmax, used to compute the weighted average in + the self-attention heads. + fpn_hidden_states (`tuple(torch.FloatTensor)`): + Tuple of `torch.FloatTensor` (one for each feature level, from high to low resolution) of shape + `(batch_size, hidden_size, height, width)`. Feature maps from the Feature Pyramid Network neck. + fpn_position_encoding (`tuple(torch.FloatTensor)`): + Tuple of `torch.FloatTensor` (one for each feature level, from high to low resolution) of shape + `(batch_size, hidden_size, height, width)`. Positional encodings corresponding to the `fpn_hidden_states`. + """ + + fpn_hidden_states: torch.FloatTensor | None = None + fpn_position_encoding: torch.FloatTensor | None = None + + +@dataclass +@auto_docstring(custom_intro="Base class for the Sam2 model's output.") +class Sam2ImageSegmentationOutput(ModelOutput): + r""" + iou_scores (`torch.FloatTensor` of shape `(batch_size, point_batch_size, num_masks)`): + The Intersection over Union (IoU) scores of the predicted masks. + pred_masks (`torch.FloatTensor` of shape `(batch_size, point_batch_size, num_masks, height, width)`): + The predicted low-resolution masks. This is an alias for `low_res_masks`. These masks need to be post-processed + by the processor to be brought to the original image size. + object_score_logits (`torch.FloatTensor` of shape `(batch_size, point_batch_size, 1)`): + Logits for the object score, indicating if an object is present. + image_embeddings (`tuple(torch.FloatTensor)`): + The features from the FPN, which are used by the mask decoder. This is a tuple of `torch.FloatTensor` where each + tensor has shape `(batch_size, channels, height, width)`. + vision_hidden_states (`tuple(torch.FloatTensor)`, *optional*, returned when `output_hidden_states=True`): + Tuple of `torch.FloatTensor` (one for the output of each stage) of shape `(batch_size, height, width, hidden_size)`. + Hidden-states of the vision model at the output of each stage. + vision_attentions (`tuple(torch.FloatTensor)`, *optional*, returned when `output_attentions=True`): + Tuple of `torch.FloatTensor` (one for each layer) of shape `(batch_size, num_heads, sequence_length, sequence_length)`. + Attentions weights of the vision model. + mask_decoder_attentions (`tuple(torch.FloatTensor)`, *optional*, returned when `output_attentions=True`): + Tuple of `torch.FloatTensor` (one for each layer) of shape `(batch_size, num_heads, sequence_length, sequence_length)`. + Attentions weights of the mask decoder. + """ + + iou_scores: torch.FloatTensor | None = None + pred_masks: torch.FloatTensor | None = None + object_score_logits: torch.FloatTensor | None = None + image_embeddings: tuple[torch.FloatTensor, ...] = None + vision_hidden_states: tuple[torch.FloatTensor, ...] | None = None + vision_attentions: tuple[torch.FloatTensor, ...] | None = None + mask_decoder_attentions: tuple[torch.FloatTensor, ...] | None = None + + +class Sam2PatchEmbeddings(nn.Module): + r""" + Turns pixel values into patch embeddings for transformer consumption. + + Args: + pixel_values (`torch.FloatTensor` of shape `(batch_size, num_channels, height, width)`): + Pixel values. Pixel values can be obtained using + [`AutoImageProcessor`]. See [`Sam2ImageProcessorFast.__call__`] for details. + + Returns: + embeddings (`torch.FloatTensor`): + Patch embeddings depend on image_size, patch_kernel_size, patch_stride and patch_padding + """ + + def __init__(self, config: Sam2HieraDetConfig): + super().__init__() + num_channels = config.num_channels + hidden_size = config.hidden_size + + self.projection = nn.Conv2d( + num_channels, + hidden_size, + kernel_size=config.patch_kernel_size, + stride=config.patch_stride, + padding=config.patch_padding, + ) + + def forward(self, pixel_values): + _, num_channels, height, width = pixel_values.shape + embeddings = self.projection(pixel_values.to(self.projection.weight.dtype)).permute(0, 2, 3, 1) + return embeddings + + +# copied and adapted from original implementation, also practically equal to DetrSinePositionEmbedding +class Sam2SinePositionEmbedding(nn.Module): + """ + This is a more standard version of the position embedding, very similar to the one used by the Attention is all you + need paper, generalized to work on images. + """ + + def __init__( + self, num_pos_feats: int = 64, temperature: int = 10000, normalize: bool = False, scale: float | None = None + ): + super().__init__() + if scale is not None and normalize is False: + raise ValueError("normalize should be True if scale is passed") + self.num_pos_feats = num_pos_feats + self.temperature = temperature + self.normalize = normalize + self.scale = 2 * math.pi if scale is None else scale + + @compile_compatible_method_lru_cache(maxsize=1) + def forward( + self, + shape: torch.Size, + device: torch.device | str, + dtype: torch.dtype, + mask: Tensor | None = None, + ) -> Tensor: + if mask is None: + mask = torch.zeros((shape[0], shape[2], shape[3]), device=device, dtype=torch.bool) + not_mask = (~mask).to(dtype) + y_embed = not_mask.cumsum(1) + x_embed = not_mask.cumsum(2) + if self.normalize: + eps = 1e-6 + y_embed = y_embed / (y_embed[:, -1:, :] + eps) * self.scale + x_embed = x_embed / (x_embed[:, :, -1:] + eps) * self.scale + + dim_t = torch.arange(self.num_pos_feats, dtype=torch.int64, device=device).to(dtype) + dim_t = self.temperature ** (2 * torch.div(dim_t, 2, rounding_mode="floor") / self.num_pos_feats) + + pos_x = x_embed[:, :, :, None] / dim_t + pos_y = y_embed[:, :, :, None] / dim_t + pos_x = torch.stack((pos_x[:, :, :, 0::2].sin(), pos_x[:, :, :, 1::2].cos()), dim=4).flatten(3) + pos_y = torch.stack((pos_y[:, :, :, 0::2].sin(), pos_y[:, :, :, 1::2].cos()), dim=4).flatten(3) + pos = torch.cat((pos_y, pos_x), dim=3).permute(0, 3, 1, 2) + return pos + + +class Sam2VisionNeck(nn.Module): + def __init__(self, config: Sam2VisionConfig): + super().__init__() + self.config = config + + self.position_encoding = Sam2SinePositionEmbedding(num_pos_feats=config.fpn_hidden_size // 2, normalize=True) + self.convs = nn.ModuleList() + for in_channels in config.backbone_channel_list: + self.convs.append( + nn.Conv2d( + in_channels=in_channels, + out_channels=config.fpn_hidden_size, + kernel_size=config.fpn_kernel_size, + stride=config.fpn_stride, + padding=config.fpn_padding, + ), + ) + self.fpn_top_down_levels = config.fpn_top_down_levels + + def forward(self, hidden_states: torch.Tensor) -> tuple[tuple[torch.Tensor, ...], tuple[torch.Tensor, ...]]: + fpn_hidden_states = () + fpn_position_encoding = () + + # forward in top-down order (from low to high resolution) + n = len(self.convs) - 1 + for i in range(n, -1, -1): + lateral_features = hidden_states[i].permute(0, 3, 1, 2) + lateral_features = self.convs[n - i](lateral_features.to(self.convs[i].weight.dtype)) + if i not in self.fpn_top_down_levels or i == n: + prev_features = lateral_features + else: + top_down_features = F.interpolate( + prev_features.to(dtype=torch.float32), + scale_factor=2.0, + mode="nearest", + align_corners=None, + antialias=False, + ).to(lateral_features.dtype) + prev_features = lateral_features + top_down_features + + prev_position_encoding = self.position_encoding( + prev_features.shape, prev_features.device, prev_features.dtype + ).to(prev_features.dtype) + + fpn_hidden_states += (prev_features,) + fpn_position_encoding += (prev_position_encoding,) + + return fpn_hidden_states, fpn_position_encoding + + +def eager_attention_forward( + module: nn.Module, + query: torch.Tensor, + key: torch.Tensor, + value: torch.Tensor, + attention_mask: torch.Tensor | None, + scaling: float, + dropout: float = 0.0, + **kwargs, +): + attn_weights = torch.matmul(query, key.transpose(2, 3)) * scaling + if attention_mask is not None: + attn_weights = attn_weights + attention_mask + + attn_weights = nn.functional.softmax(attn_weights, dim=-1, dtype=torch.float32).to(query.dtype) + attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training) + attn_output = torch.matmul(attn_weights, value) + attn_output = attn_output.transpose(1, 2).contiguous() + + return attn_output, attn_weights + + +def do_pool(x: torch.Tensor, query_stride: int | None = None) -> torch.Tensor: + if query_stride is None: + return x + # (B, H, W, C) -> (B, C, H, W) + x = x.permute(0, 3, 1, 2) + x = nn.functional.max_pool2d(x, kernel_size=query_stride, stride=query_stride, ceil_mode=False) + # (B, C, H', W') -> (B, H', W', C) + x = x.permute(0, 2, 3, 1) + return x + + +class Sam2MultiScaleAttention(nn.Module): + def __init__( + self, + config: Sam2HieraDetConfig, + dim: int, + dim_out: int, + num_attention_heads: int, + query_stride: tuple[int, int] | None = None, + ): + super().__init__() + + self.config = config + + self.dim = dim + self.dim_out = dim_out + self.query_stride = query_stride + + self.num_attention_heads = num_attention_heads + head_dim = dim_out // num_attention_heads + self.scale = head_dim**-0.5 + self.qkv = nn.Linear(dim, dim_out * 3) + self.proj = nn.Linear(dim_out, dim_out) + + self.is_causal = False + + def forward(self, hidden_states: torch.Tensor, **kwargs) -> torch.Tensor: + batch_size, height, width, _ = hidden_states.shape + # qkv with shape (B, H * W, 3, nHead, C) + qkv = self.qkv(hidden_states).reshape(batch_size, height * width, 3, self.num_attention_heads, -1) + # q, k, v with shape (B, H * W, nheads, C) + query, key, value = torch.unbind(qkv, 2) + + attn_weights = (query * self.scale) @ key.transpose(-2, -1) + attn_weights = torch.nn.functional.softmax(attn_weights, dtype=torch.float32, dim=-1).to(query.dtype) + + # Q pooling (for downsample at stage changes) + if self.query_stride: + query = do_pool(query.reshape(batch_size, height, width, -1), self.query_stride) + height, width = query.shape[1:3] # downsampled shape + query = query.reshape(batch_size, height * width, self.num_attention_heads, -1) + + # transpose query, key, value to (B, nHead, H * W, C) + query = query.transpose(1, 2) + key = key.transpose(1, 2) + value = value.transpose(1, 2) + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, eager_attention_forward + ) + attn_output, _ = attention_interface( + self, + query, + key, + value, + attention_mask=None, + is_causal=self.is_causal, + scaling=self.scale, + **kwargs, + ) + attn_output = attn_output.reshape(batch_size, height, width, -1) + + attn_output = self.proj(attn_output) + + return attn_output + + +class Sam2FeedForward(nn.Module): + def __init__( + self, + input_dim: int, + hidden_dim: int, + output_dim: int, + num_layers: int, + activation: str = "relu", + sigmoid_output: bool = False, + ): + super().__init__() + self.num_layers = num_layers + self.activation = ACT2FN[activation] + self.proj_in = nn.Linear(input_dim, hidden_dim) + self.proj_out = nn.Linear(hidden_dim, output_dim) + self.layers = nn.ModuleList([nn.Linear(hidden_dim, hidden_dim) for _ in range(num_layers - 2)]) + self.sigmoid_output = sigmoid_output + + def forward(self, hidden_states): + hidden_states = self.proj_in(hidden_states) + hidden_states = self.activation(hidden_states) + for layer in self.layers: + hidden_states = self.activation(layer(hidden_states)) + + hidden_states = self.proj_out(hidden_states) + if self.sigmoid_output: + hidden_states = F.sigmoid(hidden_states) + return hidden_states + + +def window_partition(hidden_state, window_size): + """ + Partition into non-overlapping windows with padding if needed. + + Args: + hidden_state (`torch.Tensor`): + Input tokens with [batch_size, height, width, num_channels]. + window_size (`int`): + Window size. + + Returns: + `tuple(torch.FloatTensor)` comprising various elements: + - windows: windows after partition with [batch_size * num_windows, window_size, window_size, num_channels]. + - (padded_height, padded_width): padded height and width before partition + """ + batch_size, height, width, num_channels = hidden_state.shape + + pad_height = (window_size - height % window_size) % window_size + pad_width = (window_size - width % window_size) % window_size + + # Noop in case pad_width == 0 and pad_height == 0. + hidden_state = nn.functional.pad(hidden_state, (0, 0, 0, pad_width, 0, pad_height)) + + padded_height, padded_width = height + pad_height, width + pad_width + + hidden_state = hidden_state.view( + batch_size, padded_height // window_size, window_size, padded_width // window_size, window_size, num_channels + ) + windows = hidden_state.permute(0, 1, 3, 2, 4, 5).contiguous().view(-1, window_size, window_size, num_channels) + return windows, (padded_height, padded_width) + + +def window_unpartition(windows, window_size, pad_height_width, height_width): + """ + Window unpartition into original sequences and removing padding. + + Args: + windows (`torch.Tensor`): + Input tokens with [batch_size * num_windows, window_size, window_size, num_channels]. + window_size (`int`): + Window size. + pad_height_width (`tuple[int]`): + Padded height and width (padded_height, padded_width). + height_width (`tuple[int]`): + Original height and width before padding. + + Returns: + hidden_state: unpartitioned sequences with [batch_size, height, width, num_channels]. + """ + padded_height, padded_width = pad_height_width + height, width = height_width + batch_size = windows.shape[0] // (padded_height * padded_width // window_size // window_size) + hidden_state = windows.view( + batch_size, padded_height // window_size, padded_width // window_size, window_size, window_size, -1 + ) + hidden_state = hidden_state.permute(0, 1, 3, 2, 4, 5).contiguous() + hidden_state = hidden_state.view(batch_size, padded_height, padded_width, -1) + + # We always have height <= padded_height and width <= padded_width + hidden_state = hidden_state[:, :height, :width, :].contiguous() + return hidden_state + + +class Sam2MultiScaleBlock(GradientCheckpointingLayer): + def __init__( + self, + config: Sam2HieraDetConfig, + stage_idx: int, + block_idx: int, + total_block_idx: int, + ): + super().__init__() + + # take embed dim from previous stage if first block of stage + self.dim = ( + config.embed_dim_per_stage[stage_idx - 1] + if stage_idx > 0 and block_idx == 0 + else config.embed_dim_per_stage[stage_idx] + ) + self.dim_out = config.embed_dim_per_stage[stage_idx] + self.layer_norm1 = nn.LayerNorm(self.dim, eps=config.layer_norm_eps) + # take window size from previous stage if first block of stage + self.window_size = ( + config.window_size_per_stage[stage_idx - 1] + if stage_idx > 0 and block_idx == 0 + else config.window_size_per_stage[stage_idx] + ) + self.window_size = 0 if total_block_idx in config.global_attention_blocks else self.window_size + # use query stride for first block of stage if stage is a query pool stage + self.query_stride = ( + config.query_stride if 0 < stage_idx <= config.num_query_pool_stages and block_idx == 0 else None + ) + + self.attn = Sam2MultiScaleAttention( + config, + self.dim, + self.dim_out, + num_attention_heads=config.num_attention_heads_per_stage[stage_idx], + query_stride=self.query_stride, + ) + self.layer_norm2 = nn.LayerNorm(self.dim_out, eps=config.layer_norm_eps) + self.mlp = Sam2FeedForward( + self.dim_out, + int(self.dim_out * config.mlp_ratio), + self.dim_out, + num_layers=2, + activation=config.hidden_act, + ) + if self.dim != self.dim_out: + self.proj = nn.Linear(self.dim, self.dim_out) + + def forward( + self, + hidden_states: torch.Tensor, + **kwargs: Unpack[TransformersKwargs], + ) -> torch.FloatTensor: + residual = hidden_states # batch_size, height, width, channel + + hidden_states = self.layer_norm1(hidden_states) + + # Skip connection + if self.dim != self.dim_out: + residual = do_pool(self.proj(hidden_states), self.query_stride) + + # Window partition + window_size = self.window_size + if self.window_size > 0: + H, W = hidden_states.shape[1], hidden_states.shape[2] + hidden_states, pad_hw = window_partition(hidden_states, window_size) + + # Window Attention + Q Pooling (if stage change) + attn_output = self.attn( + hidden_states=hidden_states, + **kwargs, + ) + hidden_states = attn_output + if self.query_stride: + # Shapes have changed due to Q pooling + window_size = self.window_size // self.query_stride[0] + H, W = residual.shape[1:3] + + pad_h = (window_size - H % window_size) % window_size + pad_w = (window_size - W % window_size) % window_size + pad_hw = (H + pad_h, W + pad_w) + + # Reverse window partition + if self.window_size > 0: + hidden_states = window_unpartition(hidden_states, window_size, pad_hw, (H, W)) + + hidden_states = residual + hidden_states + layernorm_output = self.layer_norm2(hidden_states) + hidden_states = hidden_states + self.mlp(layernorm_output) + + return hidden_states + + +@dataclass +@auto_docstring( + custom_intro=""" + Hiera model's outputs that also contains a pooling of the last hidden states. + """ +) +class Sam2HieraDetModelOutput(ModelOutput): + r""" + last_hidden_state (`torch.FloatTensor` of shape `(batch_size, height, width, hidden_size)`): + hidden-states at the output of the last layer of the model. + intermediate_hidden_states (`tuple[torch.FloatTensor]` of shape `(batch_size, height, width, hidden_size)`): + Sequence of hidden-states at the output of the intermediate layers of the model. + """ + + last_hidden_state: torch.FloatTensor | None = None + intermediate_hidden_states: tuple[torch.FloatTensor, ...] | None = None + hidden_states: tuple[torch.FloatTensor, ...] | None = None + attentions: tuple[torch.FloatTensor, ...] | None = None + + +@auto_docstring +class Sam2PreTrainedModel(PreTrainedModel): + config_class = Sam2Config + base_model_prefix = "sam2" + main_input_name = "pixel_values" + input_modalities = ("image",) + _supports_sdpa = True + _supports_flash_attn = True + _supports_attention_backend = True + _keys_to_ignore_on_load_unexpected = [ + r"^memory_.*", + r"^mask_downsample.*", + r"^object_pointer_proj.*", + r"^temporal_positional_encoding_projection_layer.*", + "no_memory_positional_encoding", + "no_object_pointer", + "occlusion_spatial_embedding_parameter", + ] + + @torch.no_grad() + def _init_weights(self, module): + super()._init_weights(module) + if isinstance(module, Sam2HieraDetModel): + if module.pos_embed is not None: + init.zeros_(module.pos_embed) + if module.pos_embed_window is not None: + init.zeros_(module.pos_embed_window) + elif isinstance(module, Sam2PositionalEmbedding): + init.normal_(module.positional_embedding, std=module.scale) + elif isinstance(module, Sam2Model): + if module.no_memory_embedding is not None: + init.zeros_(module.no_memory_embedding) + + +class Sam2HieraDetModel(Sam2PreTrainedModel): + config_class = Sam2HieraDetConfig + main_input_name = "pixel_values" + _can_record_outputs = { + "hidden_states": Sam2MultiScaleBlock, + "attentions": Sam2MultiScaleAttention, + } + + def __init__(self, config: Sam2HieraDetConfig): + super().__init__(config) + + self.patch_embed = Sam2PatchEmbeddings(config) + # Windowed positional embedding (https://huggingface.co/papers/2311.05613) + self.pos_embed = nn.Parameter( + torch.zeros(1, config.hidden_size, *config.window_positional_embedding_background_size) + ) + self.pos_embed_window = nn.Parameter( + torch.zeros(1, config.hidden_size, config.window_size_per_stage[0], config.window_size_per_stage[0]) + ) + self.stage_ends = (np.cumsum(config.blocks_per_stage) - 1).tolist() + self.blocks = nn.ModuleList() + total_block_idx = 0 + for stage_idx, blocks_per_stage in enumerate(config.blocks_per_stage): + for block_idx in range(blocks_per_stage): + block = Sam2MultiScaleBlock( + config=config, stage_idx=stage_idx, block_idx=block_idx, total_block_idx=total_block_idx + ) + self.blocks.append(block) + total_block_idx += 1 + + self.post_init() + + def get_input_embeddings(self): + return self.patch_embed + + def _get_pos_embed(self, hw: tuple[int, int]) -> torch.Tensor: + h, w = hw + window_embed = self.pos_embed_window + pos_embed = F.interpolate(self.pos_embed, size=(h, w), mode="bicubic") + pos_embed = pos_embed + window_embed.tile([x // y for x, y in zip(pos_embed.shape, window_embed.shape)]) + pos_embed = pos_embed.permute(0, 2, 3, 1) + return pos_embed + + @merge_with_config_defaults + @capture_outputs + def forward( + self, + pixel_values: torch.FloatTensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple | Sam2HieraDetModelOutput: + if pixel_values is None: + raise ValueError("You have to specify pixel_values") + + hidden_states = self.patch_embed(pixel_values) + hidden_states = hidden_states + self._get_pos_embed(hidden_states.shape[1:3]) + + intermediate_hidden_states = () + for i, block_module in enumerate(self.blocks): + hidden_states = block_module(hidden_states, **kwargs) + + if i in self.stage_ends: + intermediate_hidden_states = intermediate_hidden_states + (hidden_states,) + + return Sam2HieraDetModelOutput( + last_hidden_state=hidden_states, + intermediate_hidden_states=intermediate_hidden_states, + ) + + +@auto_docstring( + custom_intro=""" + The vision model from Sam without any head or projection on top. + """ +) +class Sam2VisionModel(Sam2PreTrainedModel): + config_class = Sam2VisionConfig + main_input_name = "pixel_values" + _can_record_outputs = { + "hidden_states": Sam2MultiScaleBlock, + "attentions": Sam2MultiScaleAttention, + } + + def __init__(self, config: Sam2VisionConfig): + super().__init__(config) + self.config = config + + self.backbone = AutoModel.from_config(config.backbone_config) + + self.neck = Sam2VisionNeck(config) + self.num_feature_levels = config.num_feature_levels + + self.post_init() + + def get_input_embeddings(self): + return self.backbone.get_input_embeddings() + + @can_return_tuple + def forward( + self, + pixel_values: torch.FloatTensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple | Sam2VisionEncoderOutput: + if pixel_values is None: + raise ValueError("You have to specify pixel_values") + + # Forward through backbone + backbone_output = self.backbone(pixel_values, **kwargs) + hidden_states = backbone_output.last_hidden_state + intermediate_hidden_states = backbone_output.intermediate_hidden_states + + fpn_hidden_states, fpn_position_encoding = self.neck(intermediate_hidden_states) + # Select last `num_feature_levels` feature levels from FPN and reverse order to get features from high to low resolution + fpn_hidden_states = fpn_hidden_states[-self.num_feature_levels :][::-1] + fpn_position_encoding = fpn_position_encoding[-self.num_feature_levels :][::-1] + + return Sam2VisionEncoderOutput( + last_hidden_state=hidden_states, + fpn_hidden_states=fpn_hidden_states, + fpn_position_encoding=fpn_position_encoding, + hidden_states=backbone_output.hidden_states, + attentions=backbone_output.attentions, + ) + + +class Sam2PositionalEmbedding(nn.Module): + def __init__(self, config: Sam2PromptEncoderConfig): + super().__init__() + self.scale = config.scale + positional_embedding = self.scale * torch.randn((2, config.hidden_size // 2)) + self.register_buffer("positional_embedding", positional_embedding) + + def forward(self, input_coords, input_shape=None): + """Positionally encode points that are normalized to [0,1].""" + coordinates = input_coords.clone() + + if input_shape is not None: + coordinates[:, :, :, 0] = coordinates[:, :, :, 0] / input_shape[1] + coordinates[:, :, :, 1] = coordinates[:, :, :, 1] / input_shape[0] + coordinates.to(torch.float32) + + # assuming coords are in [0, 1]^2 square and have d_1 x ... x d_n x 2 shape + coordinates = 2 * coordinates - 1 + coordinates = coordinates.to(self.positional_embedding.dtype) + coordinates = coordinates @ self.positional_embedding + coordinates = 2 * np.pi * coordinates + # outputs d_1 x ... x d_n x channel shape + return torch.cat([torch.sin(coordinates), torch.cos(coordinates)], dim=-1) + + +class Sam2MaskEmbedding(nn.Module): + def __init__(self, config: Sam2PromptEncoderConfig): + super().__init__() + self.mask_input_channels = config.mask_input_channels // 4 + self.activation = ACT2FN[config.hidden_act] + self.conv1 = nn.Conv2d(1, self.mask_input_channels, kernel_size=2, stride=2) + self.conv2 = nn.Conv2d(self.mask_input_channels, config.mask_input_channels, kernel_size=2, stride=2) + self.conv3 = nn.Conv2d(config.mask_input_channels, config.hidden_size, kernel_size=1) + self.layer_norm1 = Sam2LayerNorm( + self.mask_input_channels, eps=config.layer_norm_eps, data_format="channels_first" + ) + self.layer_norm2 = Sam2LayerNorm( + self.mask_input_channels * 4, eps=config.layer_norm_eps, data_format="channels_first" + ) + + def forward(self, masks): + hidden_states = self.conv1(masks) + hidden_states = self.layer_norm1(hidden_states) + hidden_states = self.activation(hidden_states) + + hidden_states = self.conv2(hidden_states) + hidden_states = self.layer_norm2(hidden_states) + hidden_states = self.activation(hidden_states) + dense_embeddings = self.conv3(hidden_states) + return dense_embeddings + + +class Sam2PromptEncoder(nn.Module): + def __init__(self, config: Sam2PromptEncoderConfig): + super().__init__() + self.shared_embedding = Sam2PositionalEmbedding(config) + self.mask_embed = Sam2MaskEmbedding(config) + self.no_mask_embed = nn.Embedding(1, config.hidden_size) + + self.image_embedding_size = (config.image_size // config.patch_size, config.image_size // config.patch_size) + self.mask_input_size = (4 * config.image_size // config.patch_size, 4 * config.image_size // config.patch_size) + self.input_image_size = config.image_size + + self.point_embed = nn.Embedding(config.num_point_embeddings, config.hidden_size) + self.hidden_size = config.hidden_size + self.not_a_point_embed = nn.Embedding(1, config.hidden_size) + + def _embed_points(self, points: torch.Tensor, labels: torch.Tensor, pad: bool) -> torch.Tensor: + """Embeds point prompts.""" + points = points + 0.5 # Shift to center of pixel + if pad: + points = torch.nn.functional.pad(points, (0, 0, 0, 1), mode="constant", value=0) + labels = torch.nn.functional.pad(labels, (0, 1), mode="constant", value=-1) + input_shape = (self.input_image_size, self.input_image_size) + point_embedding = self.shared_embedding(points, input_shape) + + # torch.where and expanding the labels tensor is required by the ONNX export + point_embedding = torch.where(labels[..., None] == -1, self.not_a_point_embed.weight, point_embedding) + + # This is required for the ONNX export. The dtype, device need to be explicitly + # specified as otherwise torch.onnx.export interprets as double + point_embedding = torch.where( + labels[..., None] != -10, + point_embedding, + torch.zeros_like(point_embedding), + ) + + # Add point embeddings for labels >= 0 + point_embedding = point_embedding + self.point_embed(labels.clamp(min=0)) * (labels >= 0).unsqueeze(-1) + + return point_embedding + + def _embed_boxes(self, boxes: torch.Tensor) -> torch.Tensor: + """Embeds box prompts.""" + boxes = boxes + 0.5 # Shift to center of pixel + coords = boxes.view(*boxes.shape[:2], 2, 2) + # add padding point for consistency with the original implementation + coords = torch.nn.functional.pad(coords, (0, 0, 0, 1), mode="constant", value=0) + corner_embedding = self.shared_embedding(coords, (self.input_image_size, self.input_image_size)) + corner_embedding[:, :, 0, :] += self.point_embed.weight[2] + corner_embedding[:, :, 1, :] += self.point_embed.weight[3] + corner_embedding[:, :, 2, :] = self.not_a_point_embed.weight.expand_as(corner_embedding[:, :, 2, :]) + return corner_embedding + + def forward( + self, + input_points: tuple[torch.Tensor, torch.Tensor] | None, + input_labels: torch.Tensor | None, + input_boxes: torch.Tensor | None, + input_masks: torch.Tensor | None, + ) -> tuple[torch.Tensor, torch.Tensor]: + """ + Embeds different types of prompts, returning both sparse and dense embeddings. + + Args: + points (`torch.Tensor`, *optional*): + point coordinates and labels to embed. + boxes (`torch.Tensor`, *optional*): + boxes to embed + masks (`torch.Tensor`, *optional*): + masks to embed + """ + sparse_embeddings = None + batch_size = 1 + if input_points is not None: + batch_size = input_points.shape[0] + if input_labels is None: + raise ValueError("If points are provided, labels must also be provided.") + point_embeddings = self._embed_points(input_points, input_labels, pad=(input_boxes is None)) + sparse_embeddings = point_embeddings + if input_boxes is not None: + batch_size = input_boxes.shape[0] + box_embeddings = self._embed_boxes(input_boxes) + if sparse_embeddings is None: + sparse_embeddings = box_embeddings + else: + sparse_embeddings = torch.cat([sparse_embeddings, box_embeddings], dim=2) + if input_masks is not None: + dense_embeddings = self.mask_embed(input_masks) + else: + dense_embeddings = self.no_mask_embed.weight.reshape(1, -1, 1, 1).expand( + batch_size, -1, self.image_embedding_size[0], self.image_embedding_size[1] + ) + + return sparse_embeddings, dense_embeddings + + +class Sam2Attention(nn.Module): + """ + SAM2's attention layer that allows for downscaling the size of the embedding after projection to queries, keys, and + values. + """ + + def __init__(self, config, downsample_rate=None): + super().__init__() + downsample_rate = config.attention_downsample_rate if downsample_rate is None else downsample_rate + self.config = config + self.hidden_size = config.hidden_size + self.internal_dim = config.hidden_size // downsample_rate + self.num_attention_heads = config.num_attention_heads + self.head_dim = self.internal_dim // config.num_attention_heads + self.scaling = self.head_dim**-0.5 + self.is_causal = False + + self.q_proj = nn.Linear(self.hidden_size, self.internal_dim) + self.k_proj = nn.Linear(self.hidden_size, self.internal_dim) + self.v_proj = nn.Linear(self.hidden_size, self.internal_dim) + self.o_proj = nn.Linear(self.internal_dim, self.hidden_size) + + def forward( + self, + query: torch.Tensor, + key: torch.Tensor, + value: torch.Tensor, + attention_similarity: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor, torch.Tensor]: + # Input projections + batch_size, point_batch_size = query.shape[:2] + new_shape = (batch_size * point_batch_size, -1, self.num_attention_heads, self.head_dim) + + query = self.q_proj(query).view(*new_shape).transpose(1, 2) + key = self.k_proj(key).view(*new_shape).transpose(1, 2) + value = self.v_proj(value).view(*new_shape).transpose(1, 2) + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, eager_attention_forward + ) + + if is_flash_attention_requested(self.config) and attention_similarity is not None: + # Target guided masks are represented as float masks and are incompatible with Flash Attention + # Fallback to SDPA for this call only so the rest of the model can still benefit from FA + attention_interface = ALL_ATTENTION_FUNCTIONS["sdpa"] + logger.warning_once( + "Falling back to SDPA for target-guided attention because " + "Flash Attention does not support additive bias masks." + ) + + attn_output, attn_weights = attention_interface( + self, + query, + key, + value, + attention_mask=attention_similarity, + dropout=0.0, + scaling=self.scaling, + is_causal=self.is_causal, + **kwargs, + ) + + attn_output = attn_output.reshape( + batch_size, point_batch_size, -1, self.num_attention_heads * self.head_dim + ).contiguous() + attn_output = self.o_proj(attn_output) + + return attn_output, attn_weights + + +class Sam2TwoWayAttentionBlock(GradientCheckpointingLayer): + def __init__(self, config: Sam2MaskDecoderConfig, skip_first_layer_pe: bool = False): + """ + A transformer block with four layers: + (1) self-attention of sparse inputs (2) cross attention of sparse inputs -> dense inputs (3) mlp block on + sparse inputs (4) cross attention of dense inputs -> sparse inputs + + Arguments: + config (`Sam2MaskDecoderConfig`): + The configuration file used to instantiate the block + attention_downsample_rate (*optionalk*, int, defaults to 2): + The downsample ratio of the block used to reduce the inner dim of the attention. + skip_first_layer_pe (*optional*, bool, defaults to `False`): + Whether or not to skip the addition of the query_point_embedding on the first layer. + """ + super().__init__() + self.self_attn = Sam2Attention(config, downsample_rate=1) + self.layer_norm1 = nn.LayerNorm(config.hidden_size) + + self.cross_attn_token_to_image = Sam2Attention(config) + self.layer_norm2 = nn.LayerNorm(config.hidden_size) + + self.mlp = Sam2FeedForward( + config.hidden_size, config.mlp_dim, config.hidden_size, num_layers=config.num_hidden_layers + ) + self.layer_norm3 = nn.LayerNorm(config.hidden_size) + + self.layer_norm4 = nn.LayerNorm(config.hidden_size) + self.cross_attn_image_to_token = Sam2Attention(config) + + self.skip_first_layer_pe = skip_first_layer_pe + + def forward( + self, + queries: Tensor, + keys: Tensor, + query_point_embedding: Tensor, + key_point_embedding: Tensor, + attention_similarity: Tensor, + **kwargs: Unpack[TransformersKwargs], + ): + # Self attention block + if self.skip_first_layer_pe: + queries, _ = self.self_attn(query=queries, key=queries, value=queries) + else: + query = queries + query_point_embedding + attn_out, _ = self.self_attn(query=query, key=query, value=queries) + queries = queries + attn_out + queries = self.layer_norm1(queries) + + # Cross attention block, tokens attending to image embedding + query = queries + query_point_embedding + key = keys + key_point_embedding + + attn_out, _ = self.cross_attn_token_to_image( + query=query, key=key, value=keys, attention_similarity=attention_similarity + ) + queries = queries + attn_out + + queries = self.layer_norm2(queries) + + # MLP block + mlp_out = self.mlp(queries) + queries = queries + mlp_out + queries = self.layer_norm3(queries) + + # Cross attention block, image embedding attending to tokens + query = queries + query_point_embedding + key = keys + key_point_embedding + + attn_out, _ = self.cross_attn_image_to_token(query=key, key=query, value=queries) + keys = keys + attn_out + + keys = self.layer_norm4(keys) + return queries, keys, attn_out + + +class Sam2TwoWayTransformer(nn.Module): + def __init__(self, config: Sam2MaskDecoderConfig): + super().__init__() + self.config = config + + self.num_hidden_layers = config.num_hidden_layers + self.layers = nn.ModuleList() + + for i in range(self.num_hidden_layers): + self.layers.append(Sam2TwoWayAttentionBlock(config, skip_first_layer_pe=(i == 0))) + + self.final_attn_token_to_image = Sam2Attention(config) + self.layer_norm_final_attn = nn.LayerNorm(config.hidden_size) + + def forward( + self, + point_embeddings: Tensor, + image_embeddings: Tensor, + image_positional_embeddings: Tensor, + attention_similarity: Tensor, + target_embedding=None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple | BaseModelOutput: + if image_embeddings is None: + raise ValueError("You have to specify an image_embedding") + + image_embeddings = image_embeddings.flatten(2).permute(0, 2, 1).unsqueeze(1) + image_positional_embeddings = image_positional_embeddings.flatten(2).permute(0, 2, 1).unsqueeze(1) + + # Prepare queries + queries = point_embeddings + keys = image_embeddings + + # Apply transformer blocks and final layernorm + for layer in self.layers: + if target_embedding is not None: + queries += target_embedding + + queries, keys, _ = layer( + queries=queries, + keys=keys, + query_point_embedding=point_embeddings, + key_point_embedding=image_positional_embeddings, + attention_similarity=attention_similarity, + **kwargs, + ) + # Apply the final attention layer from the points to the image + query = queries + point_embeddings + key = keys + image_positional_embeddings + + attn_out, _ = self.final_attn_token_to_image(query=query, key=key, value=keys) + + queries = queries + attn_out + queries = self.layer_norm_final_attn(queries) + return queries, keys + + +class Sam2LayerNorm(nn.LayerNorm): + r"""LayerNorm that supports two data formats: channels_last (default) or channels_first. + The ordering of the dimensions in the inputs. channels_last corresponds to inputs with shape (batch_size, height, + width, channels) while channels_first corresponds to inputs with shape (batch_size, channels, height, width). + """ + + def __init__(self, normalized_shape, *, eps=1e-6, data_format="channels_last", **kwargs): + super().__init__(normalized_shape, eps=eps, **kwargs) + if data_format not in ["channels_last", "channels_first"]: + raise NotImplementedError(f"Unsupported data format: {data_format}") + self.data_format = data_format + + def forward(self, features: torch.Tensor) -> torch.Tensor: + """ + Args: + features: Tensor of shape (batch_size, channels, height, width) OR (batch_size, height, width, channels) + """ + if self.data_format == "channels_first": + features = features.permute(0, 2, 3, 1) + features = super().forward(features) + features = features.permute(0, 3, 1, 2) + else: + features = super().forward(features) + return features + + +class Sam2MaskDecoder(nn.Module): + def __init__(self, config: Sam2MaskDecoderConfig): + super().__init__() + self.config = config + self.hidden_size = config.hidden_size + + self.num_multimask_outputs = config.num_multimask_outputs + self.num_mask_tokens = config.num_multimask_outputs + 1 + + self.iou_token = nn.Embedding(1, self.hidden_size) + self.mask_tokens = nn.Embedding(self.num_mask_tokens, self.hidden_size) + + self.transformer = Sam2TwoWayTransformer(config) + + # should we create a new class for this? + self.upscale_conv1 = nn.ConvTranspose2d(self.hidden_size, self.hidden_size // 4, kernel_size=2, stride=2) + self.upscale_conv2 = nn.ConvTranspose2d(self.hidden_size // 4, self.hidden_size // 8, kernel_size=2, stride=2) + self.upscale_layer_norm = Sam2LayerNorm(self.hidden_size // 4, data_format="channels_first") + self.activation = nn.GELU() + + mlps_list = [] + for _ in range(self.num_mask_tokens): + mlps_list += [Sam2FeedForward(self.hidden_size, self.hidden_size, self.hidden_size // 8, 3)] + self.output_hypernetworks_mlps = nn.ModuleList(mlps_list) + self.iou_prediction_head = Sam2FeedForward( + self.hidden_size, + config.iou_head_hidden_dim, + self.num_mask_tokens, + config.iou_head_depth, + sigmoid_output=True, + ) + + self.conv_s0 = nn.Conv2d(config.hidden_size, config.hidden_size // 8, kernel_size=1, stride=1) + self.conv_s1 = nn.Conv2d(config.hidden_size, config.hidden_size // 4, kernel_size=1, stride=1) + + self.obj_score_token = nn.Embedding(1, self.hidden_size) + self.pred_obj_score_head = Sam2FeedForward(self.hidden_size, self.hidden_size, 1, 3) + + self.dynamic_multimask_via_stability = config.dynamic_multimask_via_stability + self.dynamic_multimask_stability_delta = config.dynamic_multimask_stability_delta + self.dynamic_multimask_stability_thresh = config.dynamic_multimask_stability_thresh + + def forward( + self, + image_embeddings: torch.Tensor, + image_positional_embeddings: torch.Tensor, + sparse_prompt_embeddings: torch.Tensor, + dense_prompt_embeddings: torch.Tensor, + multimask_output: bool, + high_resolution_features: list[torch.Tensor], + attention_similarity: torch.Tensor | None = None, + target_embedding: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor, torch.Tensor, torch.Tensor, torch.Tensor]: + """ + Predict masks given image and prompt embeddings. + + Args: + image_embeddings (`torch.Tensor`): + The embeddings from the image encoder. + image_positional_embeddings (`torch.Tensor`): + Positional encoding with the shape of image_embeddings. + sparse_prompt_embeddings (`torch.Tensor`): + The embeddings of the points and boxes. + dense_prompt_embeddings (`torch.Tensor`): + The embeddings of the mask inputs. + multimask_output (`bool`): + Whether to return multiple masks or a single mask. + high_resolution_features (`list[torch.Tensor]`, *optional*): + The high-resolution features from the vision encoder. + attention_similarity (`torch.Tensor`, *optional*): + The attention similarity tensor. + target_embedding (`torch.Tensor`, *optional*): + The target embedding. + """ + batch_size, num_channels, height, width = image_embeddings.shape + point_batch_size = sparse_prompt_embeddings.shape[1] + # Concatenate output tokens + output_tokens = torch.cat( + [ + self.obj_score_token.weight, + self.iou_token.weight, + self.mask_tokens.weight, + ], + dim=0, + ) + output_tokens = output_tokens.repeat(batch_size, point_batch_size, 1, 1) + + if sparse_prompt_embeddings.shape[0] != 0: + tokens = torch.cat((output_tokens, sparse_prompt_embeddings), dim=2) + else: + tokens = output_tokens + point_embeddings = tokens.to(self.iou_token.weight.dtype) + + # Expand per-image data in batch direction to be per-mask + image_embeddings = image_embeddings + dense_prompt_embeddings + image_embeddings = image_embeddings.repeat_interleave(point_batch_size, dim=0) + image_positional_embeddings = image_positional_embeddings.repeat_interleave(point_batch_size, 0) + # Run the transformer + point_embeddings, image_embeddings = self.transformer( + point_embeddings=point_embeddings, + image_embeddings=image_embeddings, + image_positional_embeddings=image_positional_embeddings, + attention_similarity=attention_similarity, + target_embedding=target_embedding, + **kwargs, + ) + iou_token_out = point_embeddings[:, :, 1, :] + mask_tokens_out = point_embeddings[:, :, 2 : (2 + self.num_mask_tokens), :] + + # Upscale mask embeddings and predict masks using the mask tokens + image_embeddings = image_embeddings.transpose(2, 3).view( + batch_size * point_batch_size, num_channels, height, width + ) + + feat_s0, feat_s1 = high_resolution_features + feat_s0 = feat_s0.repeat_interleave(point_batch_size, dim=0) + feat_s1 = feat_s1.repeat_interleave(point_batch_size, dim=0) + upscaled_embedding = self.upscale_conv1(image_embeddings) + feat_s1 + upscaled_embedding = self.activation(self.upscale_layer_norm(upscaled_embedding)) + upscaled_embedding = self.activation(self.upscale_conv2(upscaled_embedding) + feat_s0) + + hyper_in_list: list[torch.Tensor] = [] + for i in range(self.num_mask_tokens): + current_mlp = self.output_hypernetworks_mlps[i] + hyper_in_list += [current_mlp(mask_tokens_out[:, :, i, :])] + hyper_in = torch.stack(hyper_in_list, dim=2) + + _, num_channels, height, width = upscaled_embedding.shape + upscaled_embedding = upscaled_embedding.view(batch_size, point_batch_size, num_channels, height * width) + masks = (hyper_in @ upscaled_embedding).view(batch_size, point_batch_size, -1, height, width) + + # Generate mask quality predictions + iou_pred = self.iou_prediction_head(iou_token_out) + object_score_logits = self.pred_obj_score_head(point_embeddings[:, :, 0, :]) + + # Select the correct mask or masks for output + if multimask_output: + mask_slice = slice(1, None) + masks = masks[:, :, mask_slice, :, :] + iou_pred = iou_pred[:, :, mask_slice] + elif self.dynamic_multimask_via_stability and not self.training: + mask_slice = slice(0, 1) + masks, iou_pred = self._dynamic_multimask_via_stability(masks, iou_pred) + else: + mask_slice = slice(0, 1) + masks = masks[:, :, mask_slice, :, :] + iou_pred = iou_pred[:, :, mask_slice] + + sam_tokens_out = mask_tokens_out[:, :, mask_slice] # [b, 3, c] shape + + return masks, iou_pred, sam_tokens_out, object_score_logits + + def _get_stability_scores(self, mask_logits): + """ + Compute stability scores of the mask logits based on the IoU between upper and + lower thresholds. + """ + mask_logits = mask_logits.flatten(-2) + stability_delta = self.dynamic_multimask_stability_delta + area_i = torch.sum(mask_logits > stability_delta, dim=-1).float() + area_u = torch.sum(mask_logits > -stability_delta, dim=-1).float() + stability_scores = torch.where(area_u > 0, area_i / area_u, 1.0) + return stability_scores + + def _dynamic_multimask_via_stability(self, all_mask_logits, all_iou_scores): + """ + When outputting a single mask, if the stability score from the current single-mask + output (based on output token 0) falls below a threshold, we instead select from + multi-mask outputs (based on output token 1~3) the mask with the highest predicted + IoU score. This is intended to ensure a valid mask for both clicking and tracking. + """ + # The best mask from multimask output tokens (1~3) + multimask_logits = all_mask_logits[:, :, 1:, :, :] + multimask_iou_scores = all_iou_scores[:, :, 1:] + best_scores_inds = torch.argmax(multimask_iou_scores, dim=-1) # [B, P] + best_scores_inds_expanded = best_scores_inds.unsqueeze(-1).unsqueeze(-1).unsqueeze(-1) + best_scores_inds_expanded = best_scores_inds_expanded.expand( + -1, -1, 1, multimask_logits.size(-2), multimask_logits.size(-1) + ) + best_multimask_logits = torch.gather(multimask_logits, 2, best_scores_inds_expanded) # [B, P, 1, H, W] + best_multimask_iou_scores = torch.gather(multimask_iou_scores, 2, best_scores_inds.unsqueeze(-1)) # [B, P, 1] + + # The mask from singlemask output token 0 and its stability score + singlemask_logits = all_mask_logits[:, :, 0:1, :, :] + singlemask_iou_scores = all_iou_scores[:, :, 0:1] + stability_scores = self._get_stability_scores(singlemask_logits) + is_stable = stability_scores >= self.dynamic_multimask_stability_thresh + + # Dynamically fall back to best multimask output upon low stability scores. + mask_logits_out = torch.where( + is_stable[..., None, None].expand_as(singlemask_logits), + singlemask_logits, + best_multimask_logits, + ) + iou_scores_out = torch.where( + is_stable.expand_as(singlemask_iou_scores), + singlemask_iou_scores, + best_multimask_iou_scores, + ) + return mask_logits_out, iou_scores_out + + +@auto_docstring( + custom_intro=""" + Segment Anything Model 2 (SAM 2) for generating segmentation masks, given an input image and + input points and labels, boxes, or masks. + """ +) +class Sam2Model(Sam2PreTrainedModel): + input_modalities = ("image", "text") + _can_record_outputs = {"mask_decoder_attentions": OutputRecorder(Sam2TwoWayAttentionBlock, index=2)} + _tied_weights_keys = {} + + def __init__(self, config: Sam2Config): + super().__init__(config) + self.shared_image_embedding = Sam2PositionalEmbedding(config.prompt_encoder_config) + self.vision_encoder = AutoModel.from_config(config.vision_config) + self.prompt_encoder = Sam2PromptEncoder(config.prompt_encoder_config) + # The module using it is not a PreTrainedModel subclass so we need this + config.mask_decoder_config._attn_implementation = config._attn_implementation + self.mask_decoder = Sam2MaskDecoder(config.mask_decoder_config) + + self.num_feature_levels = config.vision_config.num_feature_levels + self.backbone_feature_sizes = config.vision_config.backbone_feature_sizes + # a single token to indicate no memory embedding from previous frames + self.hidden_dim = config.vision_config.fpn_hidden_size + self.no_memory_embedding = torch.nn.Parameter(torch.zeros(1, 1, self.hidden_dim)) + + self.post_init() + + def get_input_embeddings(self): + return self.vision_encoder.get_input_embeddings() + + def get_image_wide_positional_embeddings(self) -> torch.Tensor: + size = self.prompt_encoder.image_embedding_size + target_device = self.shared_image_embedding.positional_embedding.device + target_dtype = self.shared_image_embedding.positional_embedding.dtype + grid = torch.ones(size, device=target_device, dtype=target_dtype) + y_embed = grid.cumsum(dim=0) - 0.5 + x_embed = grid.cumsum(dim=1) - 0.5 + y_embed = y_embed / size[0] + x_embed = x_embed / size[1] + + positional_embedding = self.shared_image_embedding(torch.stack([x_embed, y_embed], dim=-1)) + return positional_embedding.permute(2, 0, 1).unsqueeze(0) # channel x height x width + + @torch.no_grad() + def get_image_embeddings( + self, + pixel_values: torch.FloatTensor, + **kwargs: Unpack[TransformersKwargs], + ) -> list[torch.Tensor]: + r""" + Returns the image embeddings by passing the pixel values through the vision encoder. + + Args: + pixel_values (`torch.FloatTensor` of shape `(batch_size, num_channels, height, width)`): + Input pixel values + """ + batch_size = pixel_values.shape[0] + image_outputs = self.get_image_features(pixel_values, return_dict=True, **kwargs) + feature_maps = image_outputs.fpn_hidden_states + + # add no memory embedding to the last feature map + feature_maps[-1] = feature_maps[-1] + self.no_memory_embedding + + # reshape feature maps to the same shape as the backbone feature sizes + image_embeddings = [ + feat.permute(1, 2, 0).view(batch_size, -1, *feat_size) + for feat, feat_size in zip(feature_maps, self.backbone_feature_sizes) + ] + + return image_embeddings + + @torch.no_grad() + def get_prompt_embeddings( + self, + input_points: torch.FloatTensor | None = None, + input_labels: torch.LongTensor | None = None, + input_boxes: torch.FloatTensor | None = None, + input_masks: torch.LongTensor | None = None, + ): + r""" + Returns the prompt embeddings by passing the input points, labels, boxes and masks through the prompt encoder. + + Args: + input_points (`torch.FloatTensor` of shape `(batch_size, point_batch_size, num_points_per_image, 2)`): + Optional input points for the prompt encoder. The padding of the point is automatically done by the + processor. `point_batch_size` refers to the number of masks that we want the model to predict per + point. The model will output `point_batch_size` times 3 masks in total. + input_labels (`torch.LongTensor` of shape `(batch_size, point_batch_size, num_points_per_image)`): + Optional input labels for the prompt encoder. The padding of the labels is automatically done by the + processor, or can be fed by the user. + input_boxes (`torch.FloatTensor` of shape `(batch_size, num_boxes_per_image, 4)`): + Optional input boxes for the prompt encoder. The padding of the boxes is automatically done by the + processor. users can also pass manually the input boxes. + input_masks (`torch.LongTensor` of shape `(batch_size, image_size, image_size)`): + Optional input masks for the prompt encoder. + """ + prompt_output = self.prompt_encoder( + input_points=input_points, + input_labels=input_labels, + input_boxes=input_boxes, + input_masks=input_masks, + ) + return prompt_output + + @merge_with_config_defaults + @capture_outputs + @auto_docstring + def forward( + self, + pixel_values: torch.FloatTensor | None = None, + input_points: torch.FloatTensor | None = None, + input_labels: torch.LongTensor | None = None, + input_boxes: torch.FloatTensor | None = None, + input_masks: torch.LongTensor | None = None, + image_embeddings: torch.FloatTensor | None = None, + multimask_output: bool = True, + attention_similarity: torch.FloatTensor | None = None, + target_embedding: torch.FloatTensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> Sam2ImageSegmentationOutput: + r""" + input_points (`torch.FloatTensor` of shape `(batch_size, num_points, 2)`): + Input 2D spatial points, this is used by the prompt encoder to encode the prompt. Generally yields to much + better results. The points can be obtained by passing a list of list of list to the processor that will + create corresponding `torch` tensors of dimension 4. The first dimension is the image batch size, the + second dimension is the point batch size (i.e. how many segmentation masks do we want the model to predict + per input point), the third dimension is the number of points per segmentation mask (it is possible to pass + multiple points for a single mask), and the last dimension is the x (vertical) and y (horizontal) + coordinates of the point. If a different number of points is passed either for each image, or for each + mask, the processor will create "PAD" points that will correspond to the (0, 0) coordinate, and the + computation of the embedding will be skipped for these points using the labels. + input_labels (`torch.LongTensor` of shape `(batch_size, point_batch_size, num_points)`): + Input labels for the points, this is used by the prompt encoder to encode the prompt. According to the + official implementation, there are 3 types of labels + + - `1`: the point is a point that contains the object of interest + - `0`: the point is a point that does not contain the object of interest + - `-1`: the point corresponds to the background + + We added the label: + + - `-10`: the point is a padding point, thus should be ignored by the prompt encoder + + The padding labels should be automatically done by the processor. + input_boxes (`torch.FloatTensor` of shape `(batch_size, num_boxes, 4)`): + Input boxes for the points, this is used by the prompt encoder to encode the prompt. Generally yields to + much better generated masks. The boxes can be obtained by passing a list of list of list to the processor, + that will generate a `torch` tensor, with each dimension corresponding respectively to the image batch + size, the number of boxes per image and the coordinates of the top left and bottom right point of the box. + In the order (`x1`, `y1`, `x2`, `y2`): + + - `x1`: the x coordinate of the top left point of the input box + - `y1`: the y coordinate of the top left point of the input box + - `x2`: the x coordinate of the bottom right point of the input box + - `y2`: the y coordinate of the bottom right point of the input box + input_masks (`torch.FloatTensor` of shape `(batch_size, image_size, image_size)`): + SAM model also accepts segmentation masks as input. The mask will be embedded by the prompt encoder to + generate a corresponding embedding, that will be fed later on to the mask decoder. These masks needs to be + manually fed by the user, and they need to be of shape (`batch_size`, `image_size`, `image_size`). + image_embeddings (`torch.FloatTensor` of shape `(batch_size, output_channels, window_size, window_size)`): + Image embeddings, this is used by the mask decoder to generate masks and iou scores. For more memory + efficient computation, users can first retrieve the image embeddings using the `get_image_embeddings` + method, and then feed them to the `forward` method instead of feeding the `pixel_values`. + multimask_output (`bool`, *optional*): + In the original implementation and paper, the model always outputs 3 masks per image (or per point / per + bounding box if relevant). However, it is possible to just output a single mask, that corresponds to the + "best" mask, by specifying `multimask_output=False`. + attention_similarity (`torch.FloatTensor`, *optional*): + Attention similarity tensor, to be provided to the mask decoder for target-guided attention in case the + model is used for personalization as introduced in [PerSAM](https://huggingface.co/papers/2305.03048). + target_embedding (`torch.FloatTensor`, *optional*): + Embedding of the target concept, to be provided to the mask decoder for target-semantic prompting in case + the model is used for personalization as introduced in [PerSAM](https://huggingface.co/papers/2305.03048). + + Example: + + ```python + >>> from PIL import Image + >>> import httpx + >>> from io import BytesIO + >>> from transformers import AutoModel, AutoProcessor + + >>> model = AutoModel.from_pretrained("danelcsb/sam2.1_hiera_tiny") + >>> processor = AutoProcessor.from_pretrained("danelcsb/sam2.1_hiera_tiny") + + >>> url = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/model_doc/sam-car.png" + >>> with httpx.stream("GET", url) as response: + ... raw_image = Image.open(BytesIO(response.read())).convert("RGB") + >>> input_points = [[[400, 650]]] # 2D location of a window on the car + >>> inputs = processor(images=raw_image, input_points=input_points, return_tensors="pt") + + >>> # Get segmentation mask + >>> outputs = model(**inputs) + + >>> # Postprocess masks + >>> masks = processor.post_process_masks( + ... outputs.pred_masks, inputs["original_sizes"] + ... ) + ``` + """ + if not ((pixel_values is None) ^ (image_embeddings is None)): + raise ValueError("Exactly one of pixel_values or image_embeddings must be provided.") + if input_points is not None and input_boxes is not None: + if input_points.shape[1] != input_boxes.shape[1]: + raise ValueError( + f"You should provide as many bounding boxes as input points per box. Got {input_points.shape[1]} and {input_boxes.shape[1]}." + ) + + image_positional_embeddings = self.get_image_wide_positional_embeddings() + # repeat with batch size + batch_size = pixel_values.shape[0] if pixel_values is not None else image_embeddings[-1].shape[0] + image_positional_embeddings = image_positional_embeddings.repeat(batch_size, 1, 1, 1) + + vision_attentions = None + vision_hidden_states = None + + if pixel_values is not None: + image_outputs: Sam2VisionEncoderOutput = self.get_image_features(pixel_values, return_dict=True, **kwargs) + feature_maps = image_outputs.fpn_hidden_states + vision_hidden_states = image_outputs.hidden_states + vision_attentions = image_outputs.attentions + + # add no memory embedding to the last feature map + feature_maps[-1] = feature_maps[-1] + self.no_memory_embedding + + # reshape feature maps to the same shape as the backbone feature sizes + image_embeddings = [ + feat.permute(1, 2, 0).view(batch_size, -1, *feat_size) + for feat, feat_size in zip(feature_maps, self.backbone_feature_sizes) + ] + + if input_points is not None and input_labels is None: + input_labels = torch.ones_like(input_points[:, :, :, 0], dtype=torch.int, device=input_points.device) + + if input_points is None and input_boxes is None: + # If no points are provide, pad with an empty point (with label -1) + input_points = torch.zeros( + batch_size, 1, 1, 2, dtype=image_embeddings[-1].dtype, device=image_embeddings[-1].device + ) + input_labels = -torch.ones(batch_size, 1, 1, dtype=torch.int32, device=image_embeddings[-1].device) + + if input_masks is not None: + # If mask_inputs is provided, downsize it into low-res mask input if needed + # and feed it as a dense mask prompt into the SAM mask encoder + if input_masks.shape[-2:] != self.prompt_encoder.mask_input_size: + input_masks = F.interpolate( + input_masks.float(), + size=self.prompt_encoder.mask_input_size, + align_corners=False, + mode="bilinear", + antialias=True, # use antialias for downsampling + ).to(input_masks.dtype) + + sparse_embeddings, dense_embeddings = self.prompt_encoder( + input_points=input_points, + input_labels=input_labels, + input_boxes=input_boxes, + input_masks=input_masks, + ) + low_res_multimasks, iou_scores, _, object_score_logits = self.mask_decoder( + image_embeddings=image_embeddings[-1], + image_positional_embeddings=image_positional_embeddings, + sparse_prompt_embeddings=sparse_embeddings, + dense_prompt_embeddings=dense_embeddings, + multimask_output=multimask_output, + high_resolution_features=image_embeddings[:-1], + attention_similarity=attention_similarity, + target_embedding=target_embedding, + **kwargs, + ) + + return Sam2ImageSegmentationOutput( + iou_scores=iou_scores, + pred_masks=low_res_multimasks, + object_score_logits=object_score_logits, + image_embeddings=image_embeddings, + vision_hidden_states=vision_hidden_states, + vision_attentions=vision_attentions, + ) + + @can_return_tuple + @auto_docstring + def get_image_features( + self, + pixel_values: torch.FloatTensor, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple | Sam2VisionEncoderOutput: + r""" + pixel_values (`torch.FloatTensor`): + Input pixel values of shape `(batch_size, num_channels, height, width)`. + """ + vision_outputs: Sam2VisionEncoderOutput = self.vision_encoder(pixel_values, return_dict=True, **kwargs) + + feature_maps = vision_outputs.fpn_hidden_states + feature_maps_position_embeddings = vision_outputs.fpn_position_encoding + + # precompute projected level 0 and level 1 features in SAM decoder + # to avoid running it again on every SAM click + feature_maps = list(feature_maps) + feature_maps[0] = self.mask_decoder.conv_s0(feature_maps[0]) + feature_maps[1] = self.mask_decoder.conv_s1(feature_maps[1]) + + # flatten NxCxHxW to HWxNxC + feature_maps = [feature_map.flatten(2).permute(2, 0, 1) for feature_map in feature_maps] + feature_maps_position_embeddings = [ + feature_map_position_embedding.flatten(2).permute(2, 0, 1) + for feature_map_position_embedding in feature_maps_position_embeddings + ] + vision_outputs.fpn_hidden_states = feature_maps + vision_outputs.fpn_position_encoding = feature_maps_position_embeddings + + return vision_outputs + + +__all__ = ["Sam2Model", "Sam2VisionModel", "Sam2PreTrainedModel", "Sam2HieraDetModel"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam2/modular_sam2.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam2/modular_sam2.py new file mode 100644 index 0000000000000000000000000000000000000000..5ecdbfa9fafacf1af40cdfa9cf5df2a58910dfcb --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam2/modular_sam2.py @@ -0,0 +1,1470 @@ +# Copyright 2025 The Meta AI Authors and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""PyTorch SAM 2 model.""" + +from collections.abc import Callable +from dataclasses import dataclass +from typing import Union + +import numpy as np +import torch +import torch.nn as nn +import torch.nn.functional as F + +from ... import initialization as init +from ...activations import ACT2FN +from ...image_processing_utils import BatchFeature, get_size_dict +from ...image_processing_utils_fast import BaseImageProcessorFast +from ...image_utils import ( + IMAGENET_DEFAULT_MEAN, + IMAGENET_DEFAULT_STD, + ChannelDimension, + ImageInput, + PILImageResampling, + SizeDict, + pil_torch_interpolation_mapping, +) +from ...modeling_layers import GradientCheckpointingLayer +from ...modeling_outputs import BaseModelOutputWithPooling +from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel +from ...processing_utils import ImagesKwargs, Unpack +from ...utils import ModelOutput, TensorType, auto_docstring, can_return_tuple, logging +from ...utils.generic import ( + TransformersKwargs, + is_flash_attention_requested, + merge_with_config_defaults, +) +from ...utils.output_capturing import capture_outputs +from ..auto import AutoModel +from ..maskformer.modeling_maskformer import MaskFormerSinePositionEmbedding +from ..sam.image_processing_sam_fast import SamImageProcessorFast +from ..sam.modeling_sam import ( + SamLayerNorm, + SamMaskDecoder, + SamMaskEmbedding, + SamModel, + SamPromptEncoder, + SamTwoWayAttentionBlock, + SamTwoWayTransformer, + eager_attention_forward, +) +from ..vitdet.modeling_vitdet import window_partition, window_unpartition +from .configuration_sam2 import ( + Sam2Config, + Sam2HieraDetConfig, + Sam2MaskDecoderConfig, + Sam2PromptEncoderConfig, + Sam2VisionConfig, +) + + +logger = logging.get_logger(__name__) + + +class Sam2FastImageProcessorKwargs(ImagesKwargs, total=False): + r""" + mask_size (`dict[str, int]`, *optional*): + The size `{"height": int, "width": int}` to resize the segmentation maps to. + """ + + mask_size: dict[str, int] + + +@auto_docstring +class Sam2ImageProcessorFast(SamImageProcessorFast): + resample = PILImageResampling.BILINEAR + image_mean = IMAGENET_DEFAULT_MEAN + image_std = IMAGENET_DEFAULT_STD + size = {"height": 1024, "width": 1024} + mask_size = {"height": 256, "width": 256} + do_resize = True + do_rescale = True + do_normalize = True + do_convert_rgb = True + + valid_kwargs = Sam2FastImageProcessorKwargs + + # modular artefacts + do_pad = None + pad_size = None + mask_pad_size = None + + def __init__(self, **kwargs: Unpack[Sam2FastImageProcessorKwargs]): + BaseImageProcessorFast.__init__(self, **kwargs) + + def _preprocess( + self, + images: list["torch.Tensor"], + return_tensors: str | TensorType | None, + **kwargs, + ) -> "torch.Tensor": + return BaseImageProcessorFast._preprocess(self, images, return_tensors=return_tensors, **kwargs).pixel_values + + @auto_docstring + def preprocess( + self, + images: ImageInput, + segmentation_maps: ImageInput | None = None, + **kwargs: Unpack[Sam2FastImageProcessorKwargs], + ) -> BatchFeature: + r""" + segmentation_maps (`ImageInput`, *optional*): + The segmentation maps to preprocess. + """ + return super().preprocess(images, segmentation_maps, **kwargs) + + def _preprocess_image_like_inputs( + self, + images: ImageInput, + segmentation_maps: ImageInput | None, + do_convert_rgb: bool, + input_data_format: ChannelDimension, + device: Union[str, "torch.device"] | None = None, + **kwargs: Unpack[Sam2FastImageProcessorKwargs], + ) -> BatchFeature: + """ + Preprocess image-like inputs. + """ + images = self._prepare_image_like_inputs( + images=images, do_convert_rgb=do_convert_rgb, input_data_format=input_data_format, device=device + ) + original_sizes = [image.shape[-2:] for image in images] + images_kwargs = kwargs.copy() + pixel_values = self._preprocess(images, **images_kwargs) + data = { + "pixel_values": pixel_values, + "original_sizes": original_sizes, + } + + if segmentation_maps is not None: + processed_segmentation_maps = self._prepare_image_like_inputs( + images=segmentation_maps, + expected_ndims=2, + do_convert_rgb=False, + input_data_format=ChannelDimension.FIRST, + ) + + segmentation_maps_kwargs = kwargs.copy() + segmentation_maps_kwargs.update( + { + "do_normalize": False, + "do_rescale": False, + "interpolation": pil_torch_interpolation_mapping[PILImageResampling.NEAREST], + "size": segmentation_maps_kwargs.pop("mask_size"), + } + ) + processed_segmentation_maps = self._preprocess( + images=processed_segmentation_maps, **segmentation_maps_kwargs + ) + data["labels"] = processed_segmentation_maps.squeeze(1).to(torch.int64) + + return BatchFeature(data=data, tensor_type=kwargs["return_tensors"]) + + def _further_process_kwargs( + self, + size: SizeDict | None = None, + mask_size: SizeDict | None = None, + default_to_square: bool | None = None, + image_mean: float | list[float] | None = None, + image_std: float | list[float] | None = None, + data_format: ChannelDimension | None = None, + **kwargs, + ) -> dict: + """ + Update kwargs that need further processing before being validated + Can be overridden by subclasses to customize the processing of kwargs. + """ + if kwargs is None: + kwargs = {} + if size is not None: + size = SizeDict(**get_size_dict(size=size, default_to_square=default_to_square)) + if mask_size is not None: + mask_size = SizeDict(**get_size_dict(mask_size, param_name="mask_size")) + if isinstance(image_mean, list): + image_mean = tuple(image_mean) + if isinstance(image_std, list): + image_std = tuple(image_std) + if data_format is None: + data_format = ChannelDimension.FIRST + + kwargs["size"] = size + kwargs["mask_size"] = mask_size + kwargs["image_mean"] = image_mean + kwargs["image_std"] = image_std + kwargs["data_format"] = data_format + + # torch resize uses interpolation instead of resample + # Check if resample is an int before checking if it's an instance of PILImageResampling + # because if pillow < 9.1.0, resample is an int and PILImageResampling is a module. + # Checking PILImageResampling will fail with error `TypeError: isinstance() arg 2 must be a type or tuple of types`. + resample = kwargs.pop("resample") + kwargs["interpolation"] = ( + pil_torch_interpolation_mapping[resample] if isinstance(resample, (PILImageResampling, int)) else resample + ) + + return kwargs + + def _apply_non_overlapping_constraints(self, pred_masks: torch.Tensor) -> torch.Tensor: + """ + Apply non-overlapping constraints to the object scores in pred_masks. Here we + keep only the highest scoring object at each spatial location in pred_masks. + """ + batch_size = pred_masks.size(0) + if batch_size == 1: + return pred_masks + + device = pred_masks.device + # "max_obj_inds": object index of the object with the highest score at each location + max_obj_inds = torch.argmax(pred_masks, dim=0, keepdim=True) + # "batch_obj_inds": object index of each object slice (along dim 0) in `pred_masks` + batch_obj_inds = torch.arange(batch_size, device=device)[:, None, None, None] + keep = max_obj_inds == batch_obj_inds + # suppress overlapping regions' scores below -10.0 so that the foreground regions + # don't overlap (here sigmoid(-10.0)=4.5398e-05) + pred_masks = torch.where(keep, pred_masks, torch.clamp(pred_masks, max=-10.0)) + return pred_masks + + def post_process_masks( + self, + masks, + original_sizes, + mask_threshold=0.0, + binarize=True, + max_hole_area=0.0, + max_sprinkle_area=0.0, + apply_non_overlapping_constraints=False, + **kwargs, + ): + """ + Remove padding and upscale masks to the original image size. + + Args: + masks (`Union[torch.Tensor, List[torch.Tensor], np.ndarray, List[np.ndarray]]`): + Batched masks from the mask_decoder in (batch_size, num_channels, height, width) format. + original_sizes (`Union[torch.Tensor, List[Tuple[int,int]]]`): + The original sizes of each image before it was resized to the model's expected input shape, in (height, + width) format. + mask_threshold (`float`, *optional*, defaults to 0.0): + Threshold for binarization and post-processing operations. + binarize (`bool`, *optional*, defaults to `True`): + Whether to binarize the masks. + max_hole_area (`float`, *optional*, defaults to 0.0): + The maximum area of a hole to fill. + max_sprinkle_area (`float`, *optional*, defaults to 0.0): + The maximum area of a sprinkle to fill. + apply_non_overlapping_constraints (`bool`, *optional*, defaults to `False`): + Whether to apply non-overlapping constraints to the masks. + + Returns: + (`torch.Tensor`): Batched masks in batch_size, num_channels, height, width) format, where (height, width) + is given by original_size. + """ + if isinstance(original_sizes, (torch.Tensor, np.ndarray)): + original_sizes = original_sizes.tolist() + # TODO: add connected components kernel for postprocessing + output_masks = [] + for i, original_size in enumerate(original_sizes): + if isinstance(masks[i], np.ndarray): + masks[i] = torch.from_numpy(masks[i]) + elif not isinstance(masks[i], torch.Tensor): + raise TypeError("Input masks should be a list of `torch.tensors` or a list of `np.ndarray`") + interpolated_mask = F.interpolate(masks[i], original_size, mode="bilinear", align_corners=False) + if apply_non_overlapping_constraints: + interpolated_mask = self._apply_non_overlapping_constraints(interpolated_mask) + if binarize: + interpolated_mask = interpolated_mask > mask_threshold + output_masks.append(interpolated_mask) + + return output_masks + + def _get_preprocess_shape(self): + raise NotImplementedError("No _get_preprocess_shape for SAM 2.") + + def resize(self): + raise NotImplementedError("No need to override resize for SAM 2.") + + +@dataclass +@auto_docstring(custom_intro="Base class for the vision encoder's outputs.") +class Sam2VisionEncoderOutput(BaseModelOutputWithPooling): + r""" + last_hidden_state (`torch.FloatTensor` of shape `(batch_size, height, width, hidden_size)`): + Sequence of hidden-states at the output of the last layer of the model. + hidden_states (`tuple(torch.FloatTensor)`, *optional*, returned when `output_hidden_states=True` is passed or when `config.output_hidden_states=True`): + Tuple of `torch.FloatTensor` (one for the output of the embeddings, if the model has an embedding layer, + + one for the output of each stage) of shape `(batch_size, height, width, hidden_size)`. Hidden-states of the + model at the output of each stage. + attentions (`tuple(torch.FloatTensor)`, *optional*, returned when `output_attentions=True` is passed or when `config.output_attentions=True`): + Tuple of `torch.FloatTensor` (one for each layer) of shape `(batch_size, num_heads, sequence_length, + sequence_length)`. Attentions weights after the attention softmax, used to compute the weighted average in + the self-attention heads. + fpn_hidden_states (`tuple(torch.FloatTensor)`): + Tuple of `torch.FloatTensor` (one for each feature level, from high to low resolution) of shape + `(batch_size, hidden_size, height, width)`. Feature maps from the Feature Pyramid Network neck. + fpn_position_encoding (`tuple(torch.FloatTensor)`): + Tuple of `torch.FloatTensor` (one for each feature level, from high to low resolution) of shape + `(batch_size, hidden_size, height, width)`. Positional encodings corresponding to the `fpn_hidden_states`. + """ + + fpn_hidden_states: torch.FloatTensor | None = None + fpn_position_encoding: torch.FloatTensor | None = None + + +@dataclass +@auto_docstring(custom_intro="Base class for the Sam2 model's output.") +class Sam2ImageSegmentationOutput(ModelOutput): + r""" + iou_scores (`torch.FloatTensor` of shape `(batch_size, point_batch_size, num_masks)`): + The Intersection over Union (IoU) scores of the predicted masks. + pred_masks (`torch.FloatTensor` of shape `(batch_size, point_batch_size, num_masks, height, width)`): + The predicted low-resolution masks. This is an alias for `low_res_masks`. These masks need to be post-processed + by the processor to be brought to the original image size. + object_score_logits (`torch.FloatTensor` of shape `(batch_size, point_batch_size, 1)`): + Logits for the object score, indicating if an object is present. + image_embeddings (`tuple(torch.FloatTensor)`): + The features from the FPN, which are used by the mask decoder. This is a tuple of `torch.FloatTensor` where each + tensor has shape `(batch_size, channels, height, width)`. + vision_hidden_states (`tuple(torch.FloatTensor)`, *optional*, returned when `output_hidden_states=True`): + Tuple of `torch.FloatTensor` (one for the output of each stage) of shape `(batch_size, height, width, hidden_size)`. + Hidden-states of the vision model at the output of each stage. + vision_attentions (`tuple(torch.FloatTensor)`, *optional*, returned when `output_attentions=True`): + Tuple of `torch.FloatTensor` (one for each layer) of shape `(batch_size, num_heads, sequence_length, sequence_length)`. + Attentions weights of the vision model. + mask_decoder_attentions (`tuple(torch.FloatTensor)`, *optional*, returned when `output_attentions=True`): + Tuple of `torch.FloatTensor` (one for each layer) of shape `(batch_size, num_heads, sequence_length, sequence_length)`. + Attentions weights of the mask decoder. + """ + + iou_scores: torch.FloatTensor | None = None + pred_masks: torch.FloatTensor | None = None + object_score_logits: torch.FloatTensor | None = None + image_embeddings: tuple[torch.FloatTensor, ...] = None + vision_hidden_states: tuple[torch.FloatTensor, ...] | None = None + vision_attentions: tuple[torch.FloatTensor, ...] | None = None + mask_decoder_attentions: tuple[torch.FloatTensor, ...] | None = None + + +class Sam2PatchEmbeddings(nn.Module): + r""" + Turns pixel values into patch embeddings for transformer consumption. + + Args: + pixel_values (`torch.FloatTensor` of shape `(batch_size, num_channels, height, width)`): + Pixel values. Pixel values can be obtained using + [`AutoImageProcessor`]. See [`Sam2ImageProcessorFast.__call__`] for details. + + Returns: + embeddings (`torch.FloatTensor`): + Patch embeddings depend on image_size, patch_kernel_size, patch_stride and patch_padding + """ + + def __init__(self, config: Sam2HieraDetConfig): + super().__init__() + num_channels = config.num_channels + hidden_size = config.hidden_size + + self.projection = nn.Conv2d( + num_channels, + hidden_size, + kernel_size=config.patch_kernel_size, + stride=config.patch_stride, + padding=config.patch_padding, + ) + + def forward(self, pixel_values): + _, num_channels, height, width = pixel_values.shape + embeddings = self.projection(pixel_values.to(self.projection.weight.dtype)).permute(0, 2, 3, 1) + return embeddings + + +class Sam2SinePositionEmbedding(MaskFormerSinePositionEmbedding): + pass + + +class Sam2VisionNeck(nn.Module): + def __init__(self, config: Sam2VisionConfig): + super().__init__() + self.config = config + + self.position_encoding = Sam2SinePositionEmbedding(num_pos_feats=config.fpn_hidden_size // 2, normalize=True) + self.convs = nn.ModuleList() + for in_channels in config.backbone_channel_list: + self.convs.append( + nn.Conv2d( + in_channels=in_channels, + out_channels=config.fpn_hidden_size, + kernel_size=config.fpn_kernel_size, + stride=config.fpn_stride, + padding=config.fpn_padding, + ), + ) + self.fpn_top_down_levels = config.fpn_top_down_levels + + def forward(self, hidden_states: torch.Tensor) -> tuple[tuple[torch.Tensor, ...], tuple[torch.Tensor, ...]]: + fpn_hidden_states = () + fpn_position_encoding = () + + # forward in top-down order (from low to high resolution) + n = len(self.convs) - 1 + for i in range(n, -1, -1): + lateral_features = hidden_states[i].permute(0, 3, 1, 2) + lateral_features = self.convs[n - i](lateral_features.to(self.convs[i].weight.dtype)) + if i not in self.fpn_top_down_levels or i == n: + prev_features = lateral_features + else: + top_down_features = F.interpolate( + prev_features.to(dtype=torch.float32), + scale_factor=2.0, + mode="nearest", + align_corners=None, + antialias=False, + ).to(lateral_features.dtype) + prev_features = lateral_features + top_down_features + + prev_position_encoding = self.position_encoding( + prev_features.shape, prev_features.device, prev_features.dtype + ).to(prev_features.dtype) + + fpn_hidden_states += (prev_features,) + fpn_position_encoding += (prev_position_encoding,) + + return fpn_hidden_states, fpn_position_encoding + + +def do_pool(x: torch.Tensor, query_stride: int | None = None) -> torch.Tensor: + if query_stride is None: + return x + # (B, H, W, C) -> (B, C, H, W) + x = x.permute(0, 3, 1, 2) + x = nn.functional.max_pool2d(x, kernel_size=query_stride, stride=query_stride, ceil_mode=False) + # (B, C, H', W') -> (B, H', W', C) + x = x.permute(0, 2, 3, 1) + return x + + +class Sam2MultiScaleAttention(nn.Module): + def __init__( + self, + config: Sam2HieraDetConfig, + dim: int, + dim_out: int, + num_attention_heads: int, + query_stride: tuple[int, int] | None = None, + ): + super().__init__() + + self.config = config + + self.dim = dim + self.dim_out = dim_out + self.query_stride = query_stride + + self.num_attention_heads = num_attention_heads + head_dim = dim_out // num_attention_heads + self.scale = head_dim**-0.5 + self.qkv = nn.Linear(dim, dim_out * 3) + self.proj = nn.Linear(dim_out, dim_out) + + self.is_causal = False + + def forward(self, hidden_states: torch.Tensor, **kwargs) -> torch.Tensor: + batch_size, height, width, _ = hidden_states.shape + # qkv with shape (B, H * W, 3, nHead, C) + qkv = self.qkv(hidden_states).reshape(batch_size, height * width, 3, self.num_attention_heads, -1) + # q, k, v with shape (B, H * W, nheads, C) + query, key, value = torch.unbind(qkv, 2) + + attn_weights = (query * self.scale) @ key.transpose(-2, -1) + attn_weights = torch.nn.functional.softmax(attn_weights, dtype=torch.float32, dim=-1).to(query.dtype) + + # Q pooling (for downsample at stage changes) + if self.query_stride: + query = do_pool(query.reshape(batch_size, height, width, -1), self.query_stride) + height, width = query.shape[1:3] # downsampled shape + query = query.reshape(batch_size, height * width, self.num_attention_heads, -1) + + # transpose query, key, value to (B, nHead, H * W, C) + query = query.transpose(1, 2) + key = key.transpose(1, 2) + value = value.transpose(1, 2) + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, eager_attention_forward + ) + attn_output, _ = attention_interface( + self, + query, + key, + value, + attention_mask=None, + is_causal=self.is_causal, + scaling=self.scale, + **kwargs, + ) + attn_output = attn_output.reshape(batch_size, height, width, -1) + + attn_output = self.proj(attn_output) + + return attn_output + + +class Sam2FeedForward(nn.Module): + def __init__( + self, + input_dim: int, + hidden_dim: int, + output_dim: int, + num_layers: int, + activation: str = "relu", + sigmoid_output: bool = False, + ): + super().__init__() + self.num_layers = num_layers + self.activation = ACT2FN[activation] + self.proj_in = nn.Linear(input_dim, hidden_dim) + self.proj_out = nn.Linear(hidden_dim, output_dim) + self.layers = nn.ModuleList([nn.Linear(hidden_dim, hidden_dim) for _ in range(num_layers - 2)]) + self.sigmoid_output = sigmoid_output + + def forward(self, hidden_states): + hidden_states = self.proj_in(hidden_states) + hidden_states = self.activation(hidden_states) + for layer in self.layers: + hidden_states = self.activation(layer(hidden_states)) + + hidden_states = self.proj_out(hidden_states) + if self.sigmoid_output: + hidden_states = F.sigmoid(hidden_states) + return hidden_states + + +class Sam2MultiScaleBlock(GradientCheckpointingLayer): + def __init__( + self, + config: Sam2HieraDetConfig, + stage_idx: int, + block_idx: int, + total_block_idx: int, + ): + super().__init__() + + # take embed dim from previous stage if first block of stage + self.dim = ( + config.embed_dim_per_stage[stage_idx - 1] + if stage_idx > 0 and block_idx == 0 + else config.embed_dim_per_stage[stage_idx] + ) + self.dim_out = config.embed_dim_per_stage[stage_idx] + self.layer_norm1 = nn.LayerNorm(self.dim, eps=config.layer_norm_eps) + # take window size from previous stage if first block of stage + self.window_size = ( + config.window_size_per_stage[stage_idx - 1] + if stage_idx > 0 and block_idx == 0 + else config.window_size_per_stage[stage_idx] + ) + self.window_size = 0 if total_block_idx in config.global_attention_blocks else self.window_size + # use query stride for first block of stage if stage is a query pool stage + self.query_stride = ( + config.query_stride if 0 < stage_idx <= config.num_query_pool_stages and block_idx == 0 else None + ) + + self.attn = Sam2MultiScaleAttention( + config, + self.dim, + self.dim_out, + num_attention_heads=config.num_attention_heads_per_stage[stage_idx], + query_stride=self.query_stride, + ) + self.layer_norm2 = nn.LayerNorm(self.dim_out, eps=config.layer_norm_eps) + self.mlp = Sam2FeedForward( + self.dim_out, + int(self.dim_out * config.mlp_ratio), + self.dim_out, + num_layers=2, + activation=config.hidden_act, + ) + if self.dim != self.dim_out: + self.proj = nn.Linear(self.dim, self.dim_out) + + def forward( + self, + hidden_states: torch.Tensor, + **kwargs: Unpack[TransformersKwargs], + ) -> torch.FloatTensor: + residual = hidden_states # batch_size, height, width, channel + + hidden_states = self.layer_norm1(hidden_states) + + # Skip connection + if self.dim != self.dim_out: + residual = do_pool(self.proj(hidden_states), self.query_stride) + + # Window partition + window_size = self.window_size + if self.window_size > 0: + H, W = hidden_states.shape[1], hidden_states.shape[2] + hidden_states, pad_hw = window_partition(hidden_states, window_size) + + # Window Attention + Q Pooling (if stage change) + attn_output = self.attn( + hidden_states=hidden_states, + **kwargs, + ) + hidden_states = attn_output + if self.query_stride: + # Shapes have changed due to Q pooling + window_size = self.window_size // self.query_stride[0] + H, W = residual.shape[1:3] + + pad_h = (window_size - H % window_size) % window_size + pad_w = (window_size - W % window_size) % window_size + pad_hw = (H + pad_h, W + pad_w) + + # Reverse window partition + if self.window_size > 0: + hidden_states = window_unpartition(hidden_states, window_size, pad_hw, (H, W)) + + hidden_states = residual + hidden_states + layernorm_output = self.layer_norm2(hidden_states) + hidden_states = hidden_states + self.mlp(layernorm_output) + + return hidden_states + + +@dataclass +@auto_docstring( + custom_intro=""" + Hiera model's outputs that also contains a pooling of the last hidden states. + """ +) +class Sam2HieraDetModelOutput(ModelOutput): + r""" + last_hidden_state (`torch.FloatTensor` of shape `(batch_size, height, width, hidden_size)`): + hidden-states at the output of the last layer of the model. + intermediate_hidden_states (`tuple[torch.FloatTensor]` of shape `(batch_size, height, width, hidden_size)`): + Sequence of hidden-states at the output of the intermediate layers of the model. + """ + + last_hidden_state: torch.FloatTensor | None = None + intermediate_hidden_states: tuple[torch.FloatTensor, ...] | None = None + hidden_states: tuple[torch.FloatTensor, ...] | None = None + attentions: tuple[torch.FloatTensor, ...] | None = None + + +@auto_docstring +class Sam2PreTrainedModel(PreTrainedModel): + config_class = Sam2Config + base_model_prefix = "sam2" + main_input_name = "pixel_values" + input_modalities = ("image",) + _supports_sdpa = True + _supports_flash_attn = True + _supports_attention_backend = True + _keys_to_ignore_on_load_unexpected = [ + r"^memory_.*", + r"^mask_downsample.*", + r"^object_pointer_proj.*", + r"^temporal_positional_encoding_projection_layer.*", + "no_memory_positional_encoding", + "no_object_pointer", + "occlusion_spatial_embedding_parameter", + ] + + @torch.no_grad() + def _init_weights(self, module): + super()._init_weights(module) + if isinstance(module, Sam2HieraDetModel): + if module.pos_embed is not None: + init.zeros_(module.pos_embed) + if module.pos_embed_window is not None: + init.zeros_(module.pos_embed_window) + elif isinstance(module, Sam2PositionalEmbedding): + init.normal_(module.positional_embedding, std=module.scale) + elif isinstance(module, Sam2Model): + if module.no_memory_embedding is not None: + init.zeros_(module.no_memory_embedding) + + +class Sam2HieraDetModel(Sam2PreTrainedModel): + config_class = Sam2HieraDetConfig + main_input_name = "pixel_values" + _can_record_outputs = { + "hidden_states": Sam2MultiScaleBlock, + "attentions": Sam2MultiScaleAttention, + } + + def __init__(self, config: Sam2HieraDetConfig): + super().__init__(config) + + self.patch_embed = Sam2PatchEmbeddings(config) + # Windowed positional embedding (https://huggingface.co/papers/2311.05613) + self.pos_embed = nn.Parameter( + torch.zeros(1, config.hidden_size, *config.window_positional_embedding_background_size) + ) + self.pos_embed_window = nn.Parameter( + torch.zeros(1, config.hidden_size, config.window_size_per_stage[0], config.window_size_per_stage[0]) + ) + self.stage_ends = (np.cumsum(config.blocks_per_stage) - 1).tolist() + self.blocks = nn.ModuleList() + total_block_idx = 0 + for stage_idx, blocks_per_stage in enumerate(config.blocks_per_stage): + for block_idx in range(blocks_per_stage): + block = Sam2MultiScaleBlock( + config=config, stage_idx=stage_idx, block_idx=block_idx, total_block_idx=total_block_idx + ) + self.blocks.append(block) + total_block_idx += 1 + + self.post_init() + + def get_input_embeddings(self): + return self.patch_embed + + def _get_pos_embed(self, hw: tuple[int, int]) -> torch.Tensor: + h, w = hw + window_embed = self.pos_embed_window + pos_embed = F.interpolate(self.pos_embed, size=(h, w), mode="bicubic") + pos_embed = pos_embed + window_embed.tile([x // y for x, y in zip(pos_embed.shape, window_embed.shape)]) + pos_embed = pos_embed.permute(0, 2, 3, 1) + return pos_embed + + @merge_with_config_defaults + @capture_outputs + def forward( + self, + pixel_values: torch.FloatTensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple | Sam2HieraDetModelOutput: + if pixel_values is None: + raise ValueError("You have to specify pixel_values") + + hidden_states = self.patch_embed(pixel_values) + hidden_states = hidden_states + self._get_pos_embed(hidden_states.shape[1:3]) + + intermediate_hidden_states = () + for i, block_module in enumerate(self.blocks): + hidden_states = block_module(hidden_states, **kwargs) + + if i in self.stage_ends: + intermediate_hidden_states = intermediate_hidden_states + (hidden_states,) + + return Sam2HieraDetModelOutput( + last_hidden_state=hidden_states, + intermediate_hidden_states=intermediate_hidden_states, + ) + + +@auto_docstring( + custom_intro=""" + The vision model from Sam without any head or projection on top. + """ +) +class Sam2VisionModel(Sam2PreTrainedModel): + config_class = Sam2VisionConfig + main_input_name = "pixel_values" + _can_record_outputs = { + "hidden_states": Sam2MultiScaleBlock, + "attentions": Sam2MultiScaleAttention, + } + + def __init__(self, config: Sam2VisionConfig): + super().__init__(config) + self.config = config + + self.backbone = AutoModel.from_config(config.backbone_config) + + self.neck = Sam2VisionNeck(config) + self.num_feature_levels = config.num_feature_levels + + self.post_init() + + def get_input_embeddings(self): + return self.backbone.get_input_embeddings() + + @can_return_tuple + def forward( + self, + pixel_values: torch.FloatTensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple | Sam2VisionEncoderOutput: + if pixel_values is None: + raise ValueError("You have to specify pixel_values") + + # Forward through backbone + backbone_output = self.backbone(pixel_values, **kwargs) + hidden_states = backbone_output.last_hidden_state + intermediate_hidden_states = backbone_output.intermediate_hidden_states + + fpn_hidden_states, fpn_position_encoding = self.neck(intermediate_hidden_states) + # Select last `num_feature_levels` feature levels from FPN and reverse order to get features from high to low resolution + fpn_hidden_states = fpn_hidden_states[-self.num_feature_levels :][::-1] + fpn_position_encoding = fpn_position_encoding[-self.num_feature_levels :][::-1] + + return Sam2VisionEncoderOutput( + last_hidden_state=hidden_states, + fpn_hidden_states=fpn_hidden_states, + fpn_position_encoding=fpn_position_encoding, + hidden_states=backbone_output.hidden_states, + attentions=backbone_output.attentions, + ) + + +class Sam2PositionalEmbedding(nn.Module): + def __init__(self, config: Sam2PromptEncoderConfig): + super().__init__() + self.scale = config.scale + positional_embedding = self.scale * torch.randn((2, config.hidden_size // 2)) + self.register_buffer("positional_embedding", positional_embedding) + + def forward(self, input_coords, input_shape=None): + """Positionally encode points that are normalized to [0,1].""" + coordinates = input_coords.clone() + + if input_shape is not None: + coordinates[:, :, :, 0] = coordinates[:, :, :, 0] / input_shape[1] + coordinates[:, :, :, 1] = coordinates[:, :, :, 1] / input_shape[0] + coordinates.to(torch.float32) + + # assuming coords are in [0, 1]^2 square and have d_1 x ... x d_n x 2 shape + coordinates = 2 * coordinates - 1 + coordinates = coordinates.to(self.positional_embedding.dtype) + coordinates = coordinates @ self.positional_embedding + coordinates = 2 * np.pi * coordinates + # outputs d_1 x ... x d_n x channel shape + return torch.cat([torch.sin(coordinates), torch.cos(coordinates)], dim=-1) + + +class Sam2MaskEmbedding(SamMaskEmbedding): + pass + + +class Sam2PromptEncoder(SamPromptEncoder): + def __init__(self, config: Sam2PromptEncoderConfig): + nn.Module.__init__(self) + self.shared_embedding = Sam2PositionalEmbedding(config) + self.mask_embed = Sam2MaskEmbedding(config) + self.no_mask_embed = nn.Embedding(1, config.hidden_size) + + self.image_embedding_size = (config.image_size // config.patch_size, config.image_size // config.patch_size) + self.mask_input_size = (4 * config.image_size // config.patch_size, 4 * config.image_size // config.patch_size) + self.input_image_size = config.image_size + + self.point_embed = nn.Embedding(config.num_point_embeddings, config.hidden_size) + self.hidden_size = config.hidden_size + self.not_a_point_embed = nn.Embedding(1, config.hidden_size) + + def _embed_points(self, points: torch.Tensor, labels: torch.Tensor, pad: bool) -> torch.Tensor: + """Embeds point prompts.""" + points = points + 0.5 # Shift to center of pixel + if pad: + points = torch.nn.functional.pad(points, (0, 0, 0, 1), mode="constant", value=0) + labels = torch.nn.functional.pad(labels, (0, 1), mode="constant", value=-1) + input_shape = (self.input_image_size, self.input_image_size) + point_embedding = self.shared_embedding(points, input_shape) + + # torch.where and expanding the labels tensor is required by the ONNX export + point_embedding = torch.where(labels[..., None] == -1, self.not_a_point_embed.weight, point_embedding) + + # This is required for the ONNX export. The dtype, device need to be explicitly + # specified as otherwise torch.onnx.export interprets as double + point_embedding = torch.where( + labels[..., None] != -10, + point_embedding, + torch.zeros_like(point_embedding), + ) + + # Add point embeddings for labels >= 0 + point_embedding = point_embedding + self.point_embed(labels.clamp(min=0)) * (labels >= 0).unsqueeze(-1) + + return point_embedding + + def _embed_boxes(self, boxes: torch.Tensor) -> torch.Tensor: + """Embeds box prompts.""" + boxes = boxes + 0.5 # Shift to center of pixel + coords = boxes.view(*boxes.shape[:2], 2, 2) + # add padding point for consistency with the original implementation + coords = torch.nn.functional.pad(coords, (0, 0, 0, 1), mode="constant", value=0) + corner_embedding = self.shared_embedding(coords, (self.input_image_size, self.input_image_size)) + corner_embedding[:, :, 0, :] += self.point_embed.weight[2] + corner_embedding[:, :, 1, :] += self.point_embed.weight[3] + corner_embedding[:, :, 2, :] = self.not_a_point_embed.weight.expand_as(corner_embedding[:, :, 2, :]) + return corner_embedding + + +class Sam2Attention(nn.Module): + """ + SAM2's attention layer that allows for downscaling the size of the embedding after projection to queries, keys, and + values. + """ + + def __init__(self, config, downsample_rate=None): + super().__init__() + downsample_rate = config.attention_downsample_rate if downsample_rate is None else downsample_rate + self.config = config + self.hidden_size = config.hidden_size + self.internal_dim = config.hidden_size // downsample_rate + self.num_attention_heads = config.num_attention_heads + self.head_dim = self.internal_dim // config.num_attention_heads + self.scaling = self.head_dim**-0.5 + self.is_causal = False + + self.q_proj = nn.Linear(self.hidden_size, self.internal_dim) + self.k_proj = nn.Linear(self.hidden_size, self.internal_dim) + self.v_proj = nn.Linear(self.hidden_size, self.internal_dim) + self.o_proj = nn.Linear(self.internal_dim, self.hidden_size) + + def forward( + self, + query: torch.Tensor, + key: torch.Tensor, + value: torch.Tensor, + attention_similarity: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor, torch.Tensor]: + # Input projections + batch_size, point_batch_size = query.shape[:2] + new_shape = (batch_size * point_batch_size, -1, self.num_attention_heads, self.head_dim) + + query = self.q_proj(query).view(*new_shape).transpose(1, 2) + key = self.k_proj(key).view(*new_shape).transpose(1, 2) + value = self.v_proj(value).view(*new_shape).transpose(1, 2) + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, eager_attention_forward + ) + + if is_flash_attention_requested(self.config) and attention_similarity is not None: + # Target guided masks are represented as float masks and are incompatible with Flash Attention + # Fallback to SDPA for this call only so the rest of the model can still benefit from FA + attention_interface = ALL_ATTENTION_FUNCTIONS["sdpa"] + logger.warning_once( + "Falling back to SDPA for target-guided attention because " + "Flash Attention does not support additive bias masks." + ) + + attn_output, attn_weights = attention_interface( + self, + query, + key, + value, + attention_mask=attention_similarity, + dropout=0.0, + scaling=self.scaling, + is_causal=self.is_causal, + **kwargs, + ) + + attn_output = attn_output.reshape( + batch_size, point_batch_size, -1, self.num_attention_heads * self.head_dim + ).contiguous() + attn_output = self.o_proj(attn_output) + + return attn_output, attn_weights + + +class Sam2TwoWayAttentionBlock(SamTwoWayAttentionBlock, GradientCheckpointingLayer): + def __init__(self, config: Sam2MaskDecoderConfig, skip_first_layer_pe: bool = False): + nn.Module.__init__(self) + self.self_attn = Sam2Attention(config, downsample_rate=1) + self.layer_norm1 = nn.LayerNorm(config.hidden_size) + + self.cross_attn_token_to_image = Sam2Attention(config) + self.layer_norm2 = nn.LayerNorm(config.hidden_size) + + self.mlp = Sam2FeedForward( + config.hidden_size, config.mlp_dim, config.hidden_size, num_layers=config.num_hidden_layers + ) + self.layer_norm3 = nn.LayerNorm(config.hidden_size) + + self.layer_norm4 = nn.LayerNorm(config.hidden_size) + self.cross_attn_image_to_token = Sam2Attention(config) + + self.skip_first_layer_pe = skip_first_layer_pe + + +class Sam2TwoWayTransformer(SamTwoWayTransformer): + pass + + +class Sam2LayerNorm(SamLayerNorm): + pass + + +class Sam2MaskDecoder(SamMaskDecoder): + def __init__(self, config: Sam2MaskDecoderConfig): + super().__init__(config) + del self.iou_prediction_head + self.iou_prediction_head = Sam2FeedForward( + self.hidden_size, + config.iou_head_hidden_dim, + self.num_mask_tokens, + config.iou_head_depth, + sigmoid_output=True, + ) + + self.conv_s0 = nn.Conv2d(config.hidden_size, config.hidden_size // 8, kernel_size=1, stride=1) + self.conv_s1 = nn.Conv2d(config.hidden_size, config.hidden_size // 4, kernel_size=1, stride=1) + + self.obj_score_token = nn.Embedding(1, self.hidden_size) + self.pred_obj_score_head = Sam2FeedForward(self.hidden_size, self.hidden_size, 1, 3) + + self.dynamic_multimask_via_stability = config.dynamic_multimask_via_stability + self.dynamic_multimask_stability_delta = config.dynamic_multimask_stability_delta + self.dynamic_multimask_stability_thresh = config.dynamic_multimask_stability_thresh + + def _get_stability_scores(self, mask_logits): + """ + Compute stability scores of the mask logits based on the IoU between upper and + lower thresholds. + """ + mask_logits = mask_logits.flatten(-2) + stability_delta = self.dynamic_multimask_stability_delta + area_i = torch.sum(mask_logits > stability_delta, dim=-1).float() + area_u = torch.sum(mask_logits > -stability_delta, dim=-1).float() + stability_scores = torch.where(area_u > 0, area_i / area_u, 1.0) + return stability_scores + + def _dynamic_multimask_via_stability(self, all_mask_logits, all_iou_scores): + """ + When outputting a single mask, if the stability score from the current single-mask + output (based on output token 0) falls below a threshold, we instead select from + multi-mask outputs (based on output token 1~3) the mask with the highest predicted + IoU score. This is intended to ensure a valid mask for both clicking and tracking. + """ + # The best mask from multimask output tokens (1~3) + multimask_logits = all_mask_logits[:, :, 1:, :, :] + multimask_iou_scores = all_iou_scores[:, :, 1:] + best_scores_inds = torch.argmax(multimask_iou_scores, dim=-1) # [B, P] + best_scores_inds_expanded = best_scores_inds.unsqueeze(-1).unsqueeze(-1).unsqueeze(-1) + best_scores_inds_expanded = best_scores_inds_expanded.expand( + -1, -1, 1, multimask_logits.size(-2), multimask_logits.size(-1) + ) + best_multimask_logits = torch.gather(multimask_logits, 2, best_scores_inds_expanded) # [B, P, 1, H, W] + best_multimask_iou_scores = torch.gather(multimask_iou_scores, 2, best_scores_inds.unsqueeze(-1)) # [B, P, 1] + + # The mask from singlemask output token 0 and its stability score + singlemask_logits = all_mask_logits[:, :, 0:1, :, :] + singlemask_iou_scores = all_iou_scores[:, :, 0:1] + stability_scores = self._get_stability_scores(singlemask_logits) + is_stable = stability_scores >= self.dynamic_multimask_stability_thresh + + # Dynamically fall back to best multimask output upon low stability scores. + mask_logits_out = torch.where( + is_stable[..., None, None].expand_as(singlemask_logits), + singlemask_logits, + best_multimask_logits, + ) + iou_scores_out = torch.where( + is_stable.expand_as(singlemask_iou_scores), + singlemask_iou_scores, + best_multimask_iou_scores, + ) + return mask_logits_out, iou_scores_out + + def forward( + self, + image_embeddings: torch.Tensor, + image_positional_embeddings: torch.Tensor, + sparse_prompt_embeddings: torch.Tensor, + dense_prompt_embeddings: torch.Tensor, + multimask_output: bool, + high_resolution_features: list[torch.Tensor], + attention_similarity: torch.Tensor | None = None, + target_embedding: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor, torch.Tensor, torch.Tensor, torch.Tensor]: + """ + Predict masks given image and prompt embeddings. + + Args: + image_embeddings (`torch.Tensor`): + The embeddings from the image encoder. + image_positional_embeddings (`torch.Tensor`): + Positional encoding with the shape of image_embeddings. + sparse_prompt_embeddings (`torch.Tensor`): + The embeddings of the points and boxes. + dense_prompt_embeddings (`torch.Tensor`): + The embeddings of the mask inputs. + multimask_output (`bool`): + Whether to return multiple masks or a single mask. + high_resolution_features (`list[torch.Tensor]`, *optional*): + The high-resolution features from the vision encoder. + attention_similarity (`torch.Tensor`, *optional*): + The attention similarity tensor. + target_embedding (`torch.Tensor`, *optional*): + The target embedding. + """ + batch_size, num_channels, height, width = image_embeddings.shape + point_batch_size = sparse_prompt_embeddings.shape[1] + # Concatenate output tokens + output_tokens = torch.cat( + [ + self.obj_score_token.weight, + self.iou_token.weight, + self.mask_tokens.weight, + ], + dim=0, + ) + output_tokens = output_tokens.repeat(batch_size, point_batch_size, 1, 1) + + if sparse_prompt_embeddings.shape[0] != 0: + tokens = torch.cat((output_tokens, sparse_prompt_embeddings), dim=2) + else: + tokens = output_tokens + point_embeddings = tokens.to(self.iou_token.weight.dtype) + + # Expand per-image data in batch direction to be per-mask + image_embeddings = image_embeddings + dense_prompt_embeddings + image_embeddings = image_embeddings.repeat_interleave(point_batch_size, dim=0) + image_positional_embeddings = image_positional_embeddings.repeat_interleave(point_batch_size, 0) + # Run the transformer + point_embeddings, image_embeddings = self.transformer( + point_embeddings=point_embeddings, + image_embeddings=image_embeddings, + image_positional_embeddings=image_positional_embeddings, + attention_similarity=attention_similarity, + target_embedding=target_embedding, + **kwargs, + ) + iou_token_out = point_embeddings[:, :, 1, :] + mask_tokens_out = point_embeddings[:, :, 2 : (2 + self.num_mask_tokens), :] + + # Upscale mask embeddings and predict masks using the mask tokens + image_embeddings = image_embeddings.transpose(2, 3).view( + batch_size * point_batch_size, num_channels, height, width + ) + + feat_s0, feat_s1 = high_resolution_features + feat_s0 = feat_s0.repeat_interleave(point_batch_size, dim=0) + feat_s1 = feat_s1.repeat_interleave(point_batch_size, dim=0) + upscaled_embedding = self.upscale_conv1(image_embeddings) + feat_s1 + upscaled_embedding = self.activation(self.upscale_layer_norm(upscaled_embedding)) + upscaled_embedding = self.activation(self.upscale_conv2(upscaled_embedding) + feat_s0) + + hyper_in_list: list[torch.Tensor] = [] + for i in range(self.num_mask_tokens): + current_mlp = self.output_hypernetworks_mlps[i] + hyper_in_list += [current_mlp(mask_tokens_out[:, :, i, :])] + hyper_in = torch.stack(hyper_in_list, dim=2) + + _, num_channels, height, width = upscaled_embedding.shape + upscaled_embedding = upscaled_embedding.view(batch_size, point_batch_size, num_channels, height * width) + masks = (hyper_in @ upscaled_embedding).view(batch_size, point_batch_size, -1, height, width) + + # Generate mask quality predictions + iou_pred = self.iou_prediction_head(iou_token_out) + object_score_logits = self.pred_obj_score_head(point_embeddings[:, :, 0, :]) + + # Select the correct mask or masks for output + if multimask_output: + mask_slice = slice(1, None) + masks = masks[:, :, mask_slice, :, :] + iou_pred = iou_pred[:, :, mask_slice] + elif self.dynamic_multimask_via_stability and not self.training: + mask_slice = slice(0, 1) + masks, iou_pred = self._dynamic_multimask_via_stability(masks, iou_pred) + else: + mask_slice = slice(0, 1) + masks = masks[:, :, mask_slice, :, :] + iou_pred = iou_pred[:, :, mask_slice] + + sam_tokens_out = mask_tokens_out[:, :, mask_slice] # [b, 3, c] shape + + return masks, iou_pred, sam_tokens_out, object_score_logits + + +@auto_docstring( + custom_intro=""" + Segment Anything Model 2 (SAM 2) for generating segmentation masks, given an input image and + input points and labels, boxes, or masks. + """ +) +class Sam2Model(SamModel): + _tied_weights_keys = {} + + def __init__(self, config: Sam2Config): + PreTrainedModel.__init__(self, config) + self.shared_image_embedding = Sam2PositionalEmbedding(config.prompt_encoder_config) + self.vision_encoder = AutoModel.from_config(config.vision_config) + self.prompt_encoder = Sam2PromptEncoder(config.prompt_encoder_config) + # The module using it is not a PreTrainedModel subclass so we need this + config.mask_decoder_config._attn_implementation = config._attn_implementation + self.mask_decoder = Sam2MaskDecoder(config.mask_decoder_config) + + self.num_feature_levels = config.vision_config.num_feature_levels + self.backbone_feature_sizes = config.vision_config.backbone_feature_sizes + # a single token to indicate no memory embedding from previous frames + self.hidden_dim = config.vision_config.fpn_hidden_size + self.no_memory_embedding = torch.nn.Parameter(torch.zeros(1, 1, self.hidden_dim)) + + self.post_init() + + def get_image_wide_positional_embeddings(self) -> torch.Tensor: + size = self.prompt_encoder.image_embedding_size + target_device = self.shared_image_embedding.positional_embedding.device + target_dtype = self.shared_image_embedding.positional_embedding.dtype + grid = torch.ones(size, device=target_device, dtype=target_dtype) + y_embed = grid.cumsum(dim=0) - 0.5 + x_embed = grid.cumsum(dim=1) - 0.5 + y_embed = y_embed / size[0] + x_embed = x_embed / size[1] + + positional_embedding = self.shared_image_embedding(torch.stack([x_embed, y_embed], dim=-1)) + return positional_embedding.permute(2, 0, 1).unsqueeze(0) # channel x height x width + + @torch.no_grad() + def get_image_embeddings( + self, + pixel_values: torch.FloatTensor, + **kwargs: Unpack[TransformersKwargs], + ) -> list[torch.Tensor]: + r""" + Returns the image embeddings by passing the pixel values through the vision encoder. + + Args: + pixel_values (`torch.FloatTensor` of shape `(batch_size, num_channels, height, width)`): + Input pixel values + """ + batch_size = pixel_values.shape[0] + image_outputs = self.get_image_features(pixel_values, return_dict=True, **kwargs) + feature_maps = image_outputs.fpn_hidden_states + + # add no memory embedding to the last feature map + feature_maps[-1] = feature_maps[-1] + self.no_memory_embedding + + # reshape feature maps to the same shape as the backbone feature sizes + image_embeddings = [ + feat.permute(1, 2, 0).view(batch_size, -1, *feat_size) + for feat, feat_size in zip(feature_maps, self.backbone_feature_sizes) + ] + + return image_embeddings + + @can_return_tuple + @auto_docstring + def get_image_features( + self, + pixel_values: torch.FloatTensor, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple | Sam2VisionEncoderOutput: + r""" + pixel_values (`torch.FloatTensor`): + Input pixel values of shape `(batch_size, num_channels, height, width)`. + """ + vision_outputs: Sam2VisionEncoderOutput = self.vision_encoder(pixel_values, return_dict=True, **kwargs) + + feature_maps = vision_outputs.fpn_hidden_states + feature_maps_position_embeddings = vision_outputs.fpn_position_encoding + + # precompute projected level 0 and level 1 features in SAM decoder + # to avoid running it again on every SAM click + feature_maps = list(feature_maps) + feature_maps[0] = self.mask_decoder.conv_s0(feature_maps[0]) + feature_maps[1] = self.mask_decoder.conv_s1(feature_maps[1]) + + # flatten NxCxHxW to HWxNxC + feature_maps = [feature_map.flatten(2).permute(2, 0, 1) for feature_map in feature_maps] + feature_maps_position_embeddings = [ + feature_map_position_embedding.flatten(2).permute(2, 0, 1) + for feature_map_position_embedding in feature_maps_position_embeddings + ] + vision_outputs.fpn_hidden_states = feature_maps + vision_outputs.fpn_position_encoding = feature_maps_position_embeddings + + return vision_outputs + + @merge_with_config_defaults + @capture_outputs + @auto_docstring + def forward( + self, + pixel_values: torch.FloatTensor | None = None, + input_points: torch.FloatTensor | None = None, + input_labels: torch.LongTensor | None = None, + input_boxes: torch.FloatTensor | None = None, + input_masks: torch.LongTensor | None = None, + image_embeddings: torch.FloatTensor | None = None, + multimask_output: bool = True, + attention_similarity: torch.FloatTensor | None = None, + target_embedding: torch.FloatTensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> Sam2ImageSegmentationOutput: + r""" + input_points (`torch.FloatTensor` of shape `(batch_size, num_points, 2)`): + Input 2D spatial points, this is used by the prompt encoder to encode the prompt. Generally yields to much + better results. The points can be obtained by passing a list of list of list to the processor that will + create corresponding `torch` tensors of dimension 4. The first dimension is the image batch size, the + second dimension is the point batch size (i.e. how many segmentation masks do we want the model to predict + per input point), the third dimension is the number of points per segmentation mask (it is possible to pass + multiple points for a single mask), and the last dimension is the x (vertical) and y (horizontal) + coordinates of the point. If a different number of points is passed either for each image, or for each + mask, the processor will create "PAD" points that will correspond to the (0, 0) coordinate, and the + computation of the embedding will be skipped for these points using the labels. + input_labels (`torch.LongTensor` of shape `(batch_size, point_batch_size, num_points)`): + Input labels for the points, this is used by the prompt encoder to encode the prompt. According to the + official implementation, there are 3 types of labels + + - `1`: the point is a point that contains the object of interest + - `0`: the point is a point that does not contain the object of interest + - `-1`: the point corresponds to the background + + We added the label: + + - `-10`: the point is a padding point, thus should be ignored by the prompt encoder + + The padding labels should be automatically done by the processor. + input_boxes (`torch.FloatTensor` of shape `(batch_size, num_boxes, 4)`): + Input boxes for the points, this is used by the prompt encoder to encode the prompt. Generally yields to + much better generated masks. The boxes can be obtained by passing a list of list of list to the processor, + that will generate a `torch` tensor, with each dimension corresponding respectively to the image batch + size, the number of boxes per image and the coordinates of the top left and bottom right point of the box. + In the order (`x1`, `y1`, `x2`, `y2`): + + - `x1`: the x coordinate of the top left point of the input box + - `y1`: the y coordinate of the top left point of the input box + - `x2`: the x coordinate of the bottom right point of the input box + - `y2`: the y coordinate of the bottom right point of the input box + input_masks (`torch.FloatTensor` of shape `(batch_size, image_size, image_size)`): + SAM model also accepts segmentation masks as input. The mask will be embedded by the prompt encoder to + generate a corresponding embedding, that will be fed later on to the mask decoder. These masks needs to be + manually fed by the user, and they need to be of shape (`batch_size`, `image_size`, `image_size`). + image_embeddings (`torch.FloatTensor` of shape `(batch_size, output_channels, window_size, window_size)`): + Image embeddings, this is used by the mask decoder to generate masks and iou scores. For more memory + efficient computation, users can first retrieve the image embeddings using the `get_image_embeddings` + method, and then feed them to the `forward` method instead of feeding the `pixel_values`. + multimask_output (`bool`, *optional*): + In the original implementation and paper, the model always outputs 3 masks per image (or per point / per + bounding box if relevant). However, it is possible to just output a single mask, that corresponds to the + "best" mask, by specifying `multimask_output=False`. + attention_similarity (`torch.FloatTensor`, *optional*): + Attention similarity tensor, to be provided to the mask decoder for target-guided attention in case the + model is used for personalization as introduced in [PerSAM](https://huggingface.co/papers/2305.03048). + target_embedding (`torch.FloatTensor`, *optional*): + Embedding of the target concept, to be provided to the mask decoder for target-semantic prompting in case + the model is used for personalization as introduced in [PerSAM](https://huggingface.co/papers/2305.03048). + + Example: + + ```python + >>> from PIL import Image + >>> import httpx + >>> from io import BytesIO + >>> from transformers import AutoModel, AutoProcessor + + >>> model = AutoModel.from_pretrained("danelcsb/sam2.1_hiera_tiny") + >>> processor = AutoProcessor.from_pretrained("danelcsb/sam2.1_hiera_tiny") + + >>> url = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/model_doc/sam-car.png" + >>> with httpx.stream("GET", url) as response: + ... raw_image = Image.open(BytesIO(response.read())).convert("RGB") + >>> input_points = [[[400, 650]]] # 2D location of a window on the car + >>> inputs = processor(images=raw_image, input_points=input_points, return_tensors="pt") + + >>> # Get segmentation mask + >>> outputs = model(**inputs) + + >>> # Postprocess masks + >>> masks = processor.post_process_masks( + ... outputs.pred_masks, inputs["original_sizes"] + ... ) + ``` + """ + if not ((pixel_values is None) ^ (image_embeddings is None)): + raise ValueError("Exactly one of pixel_values or image_embeddings must be provided.") + if input_points is not None and input_boxes is not None: + if input_points.shape[1] != input_boxes.shape[1]: + raise ValueError( + f"You should provide as many bounding boxes as input points per box. Got {input_points.shape[1]} and {input_boxes.shape[1]}." + ) + + image_positional_embeddings = self.get_image_wide_positional_embeddings() + # repeat with batch size + batch_size = pixel_values.shape[0] if pixel_values is not None else image_embeddings[-1].shape[0] + image_positional_embeddings = image_positional_embeddings.repeat(batch_size, 1, 1, 1) + + vision_attentions = None + vision_hidden_states = None + + if pixel_values is not None: + image_outputs: Sam2VisionEncoderOutput = self.get_image_features(pixel_values, return_dict=True, **kwargs) + feature_maps = image_outputs.fpn_hidden_states + vision_hidden_states = image_outputs.hidden_states + vision_attentions = image_outputs.attentions + + # add no memory embedding to the last feature map + feature_maps[-1] = feature_maps[-1] + self.no_memory_embedding + + # reshape feature maps to the same shape as the backbone feature sizes + image_embeddings = [ + feat.permute(1, 2, 0).view(batch_size, -1, *feat_size) + for feat, feat_size in zip(feature_maps, self.backbone_feature_sizes) + ] + + if input_points is not None and input_labels is None: + input_labels = torch.ones_like(input_points[:, :, :, 0], dtype=torch.int, device=input_points.device) + + if input_points is None and input_boxes is None: + # If no points are provide, pad with an empty point (with label -1) + input_points = torch.zeros( + batch_size, 1, 1, 2, dtype=image_embeddings[-1].dtype, device=image_embeddings[-1].device + ) + input_labels = -torch.ones(batch_size, 1, 1, dtype=torch.int32, device=image_embeddings[-1].device) + + if input_masks is not None: + # If mask_inputs is provided, downsize it into low-res mask input if needed + # and feed it as a dense mask prompt into the SAM mask encoder + if input_masks.shape[-2:] != self.prompt_encoder.mask_input_size: + input_masks = F.interpolate( + input_masks.float(), + size=self.prompt_encoder.mask_input_size, + align_corners=False, + mode="bilinear", + antialias=True, # use antialias for downsampling + ).to(input_masks.dtype) + + sparse_embeddings, dense_embeddings = self.prompt_encoder( + input_points=input_points, + input_labels=input_labels, + input_boxes=input_boxes, + input_masks=input_masks, + ) + low_res_multimasks, iou_scores, _, object_score_logits = self.mask_decoder( + image_embeddings=image_embeddings[-1], + image_positional_embeddings=image_positional_embeddings, + sparse_prompt_embeddings=sparse_embeddings, + dense_prompt_embeddings=dense_embeddings, + multimask_output=multimask_output, + high_resolution_features=image_embeddings[:-1], + attention_similarity=attention_similarity, + target_embedding=target_embedding, + **kwargs, + ) + + return Sam2ImageSegmentationOutput( + iou_scores=iou_scores, + pred_masks=low_res_multimasks, + object_score_logits=object_score_logits, + image_embeddings=image_embeddings, + vision_hidden_states=vision_hidden_states, + vision_attentions=vision_attentions, + ) + + +__all__ = [ + "Sam2Model", + "Sam2VisionModel", + "Sam2PreTrainedModel", + "Sam2ImageProcessorFast", + "Sam2HieraDetModel", +] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam2/processing_sam2.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam2/processing_sam2.py new file mode 100644 index 0000000000000000000000000000000000000000..2d91799b96ac83733f3e9c493c45cb24bd501f71 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam2/processing_sam2.py @@ -0,0 +1,511 @@ +# Copyright 2025 The HuggingFace Inc. team. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +""" +Processor class for SAM2. +""" + +from copy import deepcopy + +import numpy as np + +from ...image_utils import ImageInput +from ...processing_utils import ProcessorMixin +from ...tokenization_utils_base import BatchEncoding +from ...utils import TensorType, auto_docstring, is_torch_available, logging +from ...utils.import_utils import requires + + +logger = logging.get_logger(__name__) + +if is_torch_available(): + import torch + + +@requires(backends=("torch",)) +@auto_docstring +class Sam2Processor(ProcessorMixin): + def __init__(self, image_processor, target_size: int | None = None, point_pad_value: int = -10, **kwargs): + r""" + target_size (`int`, *optional*): + The target size (in pixels) for normalizing input points and bounding boxes. If not provided, defaults + to the image processor's size configuration. All input coordinates (points and boxes) are normalized + to this size before being passed to the model. This ensures consistent coordinate representation + regardless of the original image dimensions. + point_pad_value (`int`, *optional*, defaults to -10): + The value used for padding input points when batching sequences of different lengths. This value is + used to mark padded positions and is preserved during coordinate normalization. + """ + super().__init__(image_processor, **kwargs) + self.point_pad_value = point_pad_value + self.target_size = target_size if target_size is not None else self.image_processor.size["height"] + + @auto_docstring + def __call__( + self, + images: ImageInput | None = None, + segmentation_maps: ImageInput | None = None, + input_points: list[list[list[list[float]]]] | torch.Tensor | None = None, + input_labels: list[list[list[int]]] | torch.Tensor | None = None, + input_boxes: list[list[list[float]]] | torch.Tensor | None = None, + original_sizes: list[list[float]] | torch.Tensor | None = None, + return_tensors: str | TensorType | None = None, + **kwargs, + ) -> BatchEncoding: + r""" + segmentation_maps (`ImageInput`, *optional*): + The segmentation maps to process. + input_points (`list[list[list[list[float]]]]`, `torch.Tensor`, *optional*): + The points to add to the frame. + input_labels (`list[list[list[int]]]`, `torch.Tensor`, *optional*): + The labels for the points. + input_boxes (`list[list[list[float]]]`, `torch.Tensor`, *optional*): + The bounding boxes to add to the frame. + original_sizes (`list[list[float]]`, `torch.Tensor`, *optional*): + The original sizes of the images. + + Returns: + A [`BatchEncoding`] with the following fields: + - `pixel_values` (`torch.Tensor`): The processed image(s). + - `original_sizes` (`list[list[float]]`): The original sizes of the images. + - `labels` (`torch.Tensor`): The processed segmentation maps (if provided). + - `input_points` (`torch.Tensor`): The processed points. + - `input_labels` (`torch.Tensor`): The processed labels. + - `input_boxes` (`torch.Tensor`): The processed bounding boxes. + """ + if images is not None: + encoding_image_processor = self.image_processor( + images, + segmentation_maps=segmentation_maps, + return_tensors=return_tensors, + **kwargs, + ) + elif original_sizes is not None: + if isinstance(original_sizes, torch.Tensor): + original_sizes = original_sizes.cpu().tolist() + encoding_image_processor = BatchEncoding({"original_sizes": original_sizes}, tensor_type=return_tensors) + else: + raise ValueError("Either images or original_sizes must be provided") + + # pop arguments that are not used in the forward but used nevertheless + original_sizes = encoding_image_processor["original_sizes"] + # Check original_sizes is of length 1 or len(images) + if images is not None and len(original_sizes) != 1 and len(original_sizes) != len(images): + raise ValueError( + "original_sizes must be of length 1 or len(images). If you are passing a single image, you must pass a single original_size." + ) + + # Process input points, labels, and boxes if provided + if input_points is not None or input_labels is not None or input_boxes is not None: + # Validate and convert inputs to standardized format + processed_points = self._validate_single_input( + input_points, + expected_depth=4, + input_name="points", + expected_format="[image level, object level, point level, point coordinates]", + expected_coord_size=2, + ) + processed_labels = self._validate_single_input( + input_labels, + expected_depth=3, + input_name="labels", + expected_format="[image level, object level, point level]", + ) + processed_boxes = self._validate_single_input( + input_boxes, + expected_depth=3, + input_name="boxes", + expected_format="[image level, box level, box coordinates]", + expected_coord_size=4, + ) + + # Get padding requirements for all inputs + if processed_points is not None: + points_max_dims = self._get_nested_dimensions(processed_points)[:3] + if processed_labels is not None: + labels_max_dims = self._get_nested_dimensions(processed_labels)[:3] + if processed_boxes is not None: + boxes_max_dims = self._get_nested_dimensions(processed_boxes)[:2] + + # Ensure points and labels have consistent dimensions + if processed_points is not None and processed_labels is not None: + if points_max_dims != labels_max_dims: + raise ValueError( + "Input points and labels have inconsistent dimensions. Please ensure they have the same dimensions." + ) + + # Check that boxes don't need padding (model limitation) + if processed_boxes is not None and len(processed_boxes) >= 2: + if any(len(img_boxes) < boxes_max_dims[1] for img_boxes in processed_boxes): + raise ValueError( + "Input boxes have inconsistent dimensions that would require padding, " + "but boxes cannot be padded due to model limitations. " + "Please ensure all images have the same number of boxes." + ) + + # Pad and normalize all inputs to final tensor format + if processed_points is not None: + padded_points = self._pad_nested_list(processed_points, points_max_dims + [2]) + final_points = torch.tensor(padded_points, dtype=torch.float32) + self._normalize_tensor_coordinates(final_points, original_sizes, preserve_padding=True) + encoding_image_processor.update({"input_points": final_points}) + + if processed_labels is not None: + padded_labels = self._pad_nested_list(processed_labels, labels_max_dims) + final_labels = torch.tensor(padded_labels, dtype=torch.int64) + encoding_image_processor.update({"input_labels": final_labels}) + + if processed_boxes is not None: + final_boxes = torch.tensor(processed_boxes, dtype=torch.float32) + self._normalize_tensor_coordinates(final_boxes, original_sizes, is_bounding_box=True) + encoding_image_processor.update({"input_boxes": final_boxes}) + + return encoding_image_processor + + def _normalize_coordinates( + self, target_size: int, coords: "torch.Tensor", original_size, is_bounding_box=False + ) -> "torch.Tensor": + """ + Expects a numpy array of length 2 in the final dimension. Requires the original image size in (H, W) format. + + Args: + target_size (`int`): + The target size of the image. + coords (`torch.Tensor`): + The coordinates to be normalized. + original_size (`tuple`): + The original size of the image. + is_bounding_box (`bool`, *optional*, defaults to `False`): + Whether the coordinates are bounding boxes. + """ + old_h, old_w = original_size + new_h, new_w = target_size, target_size + coords = deepcopy(coords).float() + + if is_bounding_box: + coords = coords.reshape(-1, 2, 2) + coords[..., 0] = coords[..., 0] * (new_w / old_w) + coords[..., 1] = coords[..., 1] * (new_h / old_h) + + if is_bounding_box: + coords = coords.reshape(-1, 4) + + return coords + + def _convert_to_nested_list(self, data, expected_depth, current_depth=0): + """ + Recursively convert various input formats (tensors, numpy arrays, lists) to nested lists. + + Args: + data: Input data in any format + expected_depth: Expected nesting depth + current_depth: Current depth in recursion + + Returns: + Nested list representation of the data + """ + if data is None: + return None + + # Convert tensor/numpy to list if we're at a leaf level or if it's a multi-dimensional array + if isinstance(data, torch.Tensor): # PyTorch tensor + if current_depth == expected_depth - 2 or len(data.shape) <= 2: # At coordinate level or small tensor + return data.numpy().tolist() + else: + return [self._convert_to_nested_list(item, expected_depth, current_depth + 1) for item in data] + elif isinstance(data, np.ndarray): # NumPy array + if current_depth == expected_depth - 2 or len(data.shape) <= 2: # At coordinate level or small array + return data.tolist() + else: + return [self._convert_to_nested_list(item, expected_depth, current_depth + 1) for item in data] + elif isinstance(data, list): + if current_depth == expected_depth: + # We've reached the expected depth, return as is + return data + else: + # Continue recursion + return [self._convert_to_nested_list(item, expected_depth, current_depth + 1) for item in data] + elif isinstance(data, (int, float)): + return data + else: + raise TypeError(f"Unsupported data type: {type(data)}") + + def _get_nested_dimensions(self, nested_list, max_dims=None): + """ + Get the maximum dimensions at each level of nesting. + + Args: + nested_list (`list`): + Nested list structure. + max_dims (`list`, *optional*): + Current maximum dimensions (for recursion). + + Returns: + `list`: A list of maximum dimensions for each nesting level. + """ + if max_dims is None: + max_dims = [] + + if not isinstance(nested_list, list): + return max_dims + + if len(max_dims) == 0: + max_dims.append(len(nested_list)) + else: + max_dims[0] = max(max_dims[0], len(nested_list)) + + if len(nested_list) > 0: + for item in nested_list: + if isinstance(item, list): + sub_dims = self._get_nested_dimensions(item) + # Merge sub_dims into max_dims + for i, dim in enumerate(sub_dims): + if i + 1 >= len(max_dims): + max_dims.append(dim) + else: + max_dims[i + 1] = max(max_dims[i + 1], dim) + + return max_dims + + def _pad_nested_list(self, nested_list, target_dims, current_level=0, pad_value=None): + """ + Recursively pad a nested list to match target dimensions. + + Args: + nested_list (`list`): + Nested list to pad. + target_dims (`list`): + Target dimensions for each level. + current_level (`int`, *optional*, defaults to 0): + Current nesting level. + pad_value (`int`, *optional*): + Value to use for padding. + + Returns: + `list`: The padded nested list. + """ + if pad_value is None: + pad_value = self.point_pad_value + + if current_level >= len(target_dims): + return nested_list + + # Ensure we have a list + if not isinstance(nested_list, list): + nested_list = [nested_list] + + # Pad current level + current_size = len(nested_list) + target_size = target_dims[current_level] + + # Pad with appropriate values + if current_level == len(target_dims) - 1: + # At the coordinate level, pad with pad_value + nested_list.extend([pad_value] * (target_size - current_size)) + else: + # At higher levels, pad with nested structures + if current_size > 0: + # Create appropriately sized template + if current_level < len(target_dims) - 2: + # For non-coordinate levels, create empty nested structure + template_dims = target_dims[current_level + 1 :] + template = self._create_empty_nested_structure(template_dims, pad_value) + else: + # For coordinate level, create list of pad_values + template = [pad_value] * target_dims[current_level + 1] + + nested_list.extend([deepcopy(template) for _ in range(target_size - current_size)]) + else: + # Create from scratch + template_dims = target_dims[current_level + 1 :] + template = self._create_empty_nested_structure(template_dims, pad_value) + nested_list.extend([deepcopy(template) for _ in range(target_size)]) + + # Recursively pad sublists + if current_level < len(target_dims) - 1: + for i in range(len(nested_list)): + if isinstance(nested_list[i], list): + nested_list[i] = self._pad_nested_list(nested_list[i], target_dims, current_level + 1, pad_value) + + return nested_list + + def _create_empty_nested_structure(self, dims, pad_value): + """ + Create an empty nested structure with given dimensions filled with pad_value. + + Args: + dims (`list`): + The dimensions of the nested structure. + pad_value (`int`): + The value to fill the structure with. + """ + if len(dims) == 1: + return [pad_value] * dims[0] + else: + return [self._create_empty_nested_structure(dims[1:], pad_value) for _ in range(dims[0])] + + def _get_nesting_level(self, input_list): + """ + Get the nesting level of a list structure. + + Args: + input_list (`list`): + The list to get the nesting level of. + """ + if isinstance(input_list, list): + if len(input_list) == 0: + return 1 + return 1 + self._get_nesting_level(input_list[0]) + elif isinstance(input_list, (np.ndarray, torch.Tensor)): + # For arrays/tensors, the nesting level is the number of dimensions + return len(input_list.shape) + return 0 + + def _validate_single_input( + self, + data: torch.Tensor | np.ndarray | list, + expected_depth: int, + input_name: str, + expected_format: str, + expected_coord_size: int | None = None, + ) -> list: + """ + Validate a single input by ensuring proper nesting and raising an error if the input is not valid. + + Args: + data (`torch.Tensor`, `np.ndarray`, or `list`): + Input data to process. + expected_depth (`int`): + Expected nesting depth. + input_name (`str`): + Name of the input for error messages. + expected_format (`str`): + The expected format of the input. + expected_coord_size (`int`, *optional*): + Expected coordinate size (2 for points, 4 for boxes, None for labels). + . + """ + if data is None: + return None + + # Handle tensors and numpy arrays first + if isinstance(data, (torch.Tensor, np.ndarray)): + # For tensors/arrays, we can directly check the number of dimensions + if data.ndim != expected_depth: + raise ValueError( + f"Input {input_name} must be a tensor/array with {expected_depth} dimensions. The expected nesting format is {expected_format}. Got {data.ndim} dimensions." + ) + elif expected_coord_size is not None: + if data.shape[-1] != expected_coord_size: + raise ValueError( + f"Input {input_name} must be a tensor/array with {expected_coord_size} as the last dimension, got {data.shape[-1]}." + ) + return self._convert_to_nested_list(data, expected_depth) + + # Handle nested lists + if isinstance(data, list): + current_depth = self._get_nesting_level(data) + if current_depth != expected_depth: + raise ValueError( + f"Input {input_name} must be a nested list with {expected_depth} levels. The expected nesting format is {expected_format}. Got {current_depth} levels." + ) + return self._convert_to_nested_list(data, expected_depth) + + def _normalize_tensor_coordinates(self, tensor, original_sizes, is_bounding_box=False, preserve_padding=False): + """ + Helper method to normalize coordinates in a tensor across multiple images. + + Args: + tensor (`torch.Tensor`): + Input tensor with coordinates. + original_sizes (`list`): + Original image sizes. + is_bounding_box (`bool`, *optional*, defaults to `False`): + Whether coordinates are bounding boxes. + preserve_padding (`bool`, *optional*, defaults to `False`): + Whether to preserve padding values (for points). + """ + if preserve_padding: + # For points: avoid normalizing pad values + mask = tensor != self.point_pad_value + coord_mask = mask.all(dim=-1, keepdim=True) + + for img_idx in range(len(original_sizes)): + if img_idx < tensor.shape[0]: + original_size = original_sizes[img_idx] if img_idx < len(original_sizes) else original_sizes[0] + normalized_coords = self._normalize_coordinates( + self.target_size, tensor[img_idx], original_size, is_bounding_box=is_bounding_box + ) + + if preserve_padding: + # Only update non-padded values + img_mask = coord_mask[img_idx] + tensor[img_idx] = torch.where( + img_mask.expand_as(tensor[img_idx]), normalized_coords, tensor[img_idx] + ) + else: + tensor[img_idx] = normalized_coords + + def post_process_masks( + self, + masks, + original_sizes, + mask_threshold=0.0, + binarize=True, + max_hole_area=0.0, + max_sprinkle_area=0.0, + apply_non_overlapping_constraints=False, + **kwargs, + ): + """ + Remove padding and upscale masks to the original image size. + + Args: + masks (`Union[List[torch.Tensor], List[np.ndarray]]`): + Batched masks from the mask_decoder in (batch_size, num_channels, height, width) format. + original_sizes (`Union[torch.Tensor, List[Tuple[int,int]]]`): + The original sizes of each image before it was resized to the model's expected input shape, in (height, + width) format. + mask_threshold (`float`, *optional*, defaults to 0.0): + Threshold for binarization and post-processing operations. + binarize (`bool`, *optional*, defaults to `True`): + Whether to binarize the masks. + max_hole_area (`float`, *optional*, defaults to 0.0): + The maximum area of a hole to fill. + max_sprinkle_area (`float`, *optional*, defaults to 0.0): + The maximum area of a sprinkle to fill. + apply_non_overlapping_constraints (`bool`, *optional*, defaults to `False`): + Whether to apply non-overlapping constraints to the masks. + + Returns: + (`torch.Tensor`): Batched masks in batch_size, num_channels, height, width) format, where (height, width) + is given by original_size. + """ + return self.image_processor.post_process_masks( + masks, + original_sizes, + mask_threshold, + binarize, + max_hole_area, + max_sprinkle_area, + apply_non_overlapping_constraints, + **kwargs, + ) + + @property + def model_input_names(self): + image_processor_input_names = self.image_processor.model_input_names + return list(image_processor_input_names + ["original_sizes"]) + + +__all__ = ["Sam2Processor"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam2_video/__init__.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam2_video/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..565e8bcaf4d0d327ff1dbf21343008b24e0e844b --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam2_video/__init__.py @@ -0,0 +1,29 @@ +# Copyright 2025 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from typing import TYPE_CHECKING + +from ...utils import _LazyModule +from ...utils.import_utils import define_import_structure + + +if TYPE_CHECKING: + from .configuration_sam2_video import * + from .modeling_sam2_video import * + from .processing_sam2_video import * + from .video_processing_sam2_video import * +else: + import sys + + _file = globals()["__file__"] + sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__) diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam2_video/configuration_sam2_video.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam2_video/configuration_sam2_video.py new file mode 100644 index 0000000000000000000000000000000000000000..ecfcd10aa27b4d0fa03a91356277f3d1d00b3f4a --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam2_video/configuration_sam2_video.py @@ -0,0 +1,394 @@ +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# This file was automatically generated from src/transformers/models/sam2_video/modular_sam2_video.py. +# Do NOT edit this file manually as any edits will be overwritten by the generation of +# the file from the modular. If any change should be done, please apply the change to the +# modular_sam2_video.py file directly. One of our CI enforces this. +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# Copyright 2025 The Meta AI Authors and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from ...configuration_utils import PreTrainedConfig +from ..auto import CONFIG_MAPPING, AutoConfig + + +class Sam2VideoPromptEncoderConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`Sam2VideoPromptEncoder`]. The [`Sam2VideoPromptEncoder`] + module is used to encode the input 2D points and bounding boxes. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + hidden_size (`int`, *optional*, defaults to 256): + Dimensionality of the hidden states. + image_size (`int`, *optional*, defaults to 1024): + The expected output resolution of the image. + patch_size (`int`, *optional*, defaults to 16): + The size (resolution) of each patch. + mask_input_channels (`int`, *optional*, defaults to 16): + The number of channels to be fed to the `MaskDecoder` module. + num_point_embeddings (`int`, *optional*, defaults to 4): + The number of point embeddings to be used. + hidden_act (`str`, *optional*, defaults to `"gelu"`): + The non-linear activation function in the encoder and pooler. + layer_norm_eps (`float`, *optional*, defaults to 1e-06): + The epsilon used by the layer normalization layers. + scale (`float`, *optional*, defaults to 1): + The scale factor for the prompt encoder. + """ + + base_config_key = "prompt_encoder_config" + + def __init__( + self, + hidden_size=256, + image_size=1024, + patch_size=16, + mask_input_channels=16, + num_point_embeddings=4, + hidden_act="gelu", + layer_norm_eps=1e-6, + scale=1, + **kwargs, + ): + super().__init__(**kwargs) + self.hidden_size = hidden_size + self.image_size = image_size + self.patch_size = patch_size + self.mask_input_channels = mask_input_channels + self.num_point_embeddings = num_point_embeddings + self.hidden_act = hidden_act + self.layer_norm_eps = layer_norm_eps + self.scale = scale + + +class Sam2VideoMaskDecoderConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`Sam2VideoMaskDecoder`]. It is used to instantiate a SAM2_VIDEO + memory encoder according to the specified arguments, defining the model architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + hidden_size (`int`, *optional*, defaults to 256): + Dimensionality of the hidden states. + hidden_act (`str`, *optional*, defaults to `"gelu"`): + The non-linear activation function in the SAM2_VIDEO mask decoder. + mlp_dim (`int`, *optional*, defaults to 2048): + The dimension of the MLP in the two-way transformer. + num_hidden_layers (`int`, *optional*, defaults to 2): + The number of hidden layers in the two-way transformer. + num_attention_heads (`int`, *optional*, defaults to 8): + The number of attention heads in the two-way transformer. + attention_downsample_rate (`int`, *optional*, defaults to 2): + The downsample rate for the attention layers. + num_multimask_outputs (`int`, *optional*, defaults to 3): + The number of multimask outputs. + iou_head_depth (`int`, *optional*, defaults to 3): + The depth of the IoU head. + iou_head_hidden_dim (`int`, *optional*, defaults to 256): + The hidden dimension of the IoU head. + dynamic_multimask_via_stability (`bool`, *optional*, defaults to `True`): + Whether to use dynamic multimask via stability. + dynamic_multimask_stability_delta (`float`, *optional*, defaults to 0.05): + The stability delta for the dynamic multimask. + dynamic_multimask_stability_thresh (`float`, *optional*, defaults to 0.98): + The stability threshold for the dynamic multimask. + + """ + + base_config_key = "mask_decoder_config" + + def __init__( + self, + hidden_size=256, + hidden_act="gelu", + mlp_dim=2048, + num_hidden_layers=2, + num_attention_heads=8, + attention_downsample_rate=2, + num_multimask_outputs=3, + iou_head_depth=3, + iou_head_hidden_dim=256, + dynamic_multimask_via_stability=True, + dynamic_multimask_stability_delta=0.05, + dynamic_multimask_stability_thresh=0.98, + **kwargs, + ): + super().__init__(**kwargs) + + self.hidden_size = hidden_size + self.num_multimask_outputs = num_multimask_outputs + self.hidden_act = hidden_act + self.iou_head_depth = iou_head_depth + self.iou_head_hidden_dim = iou_head_hidden_dim + self.dynamic_multimask_via_stability = dynamic_multimask_via_stability + self.dynamic_multimask_stability_delta = dynamic_multimask_stability_delta + self.dynamic_multimask_stability_thresh = dynamic_multimask_stability_thresh + + # TwoWayTransformer configuration + self.num_hidden_layers = num_hidden_layers + self.hidden_size = hidden_size + self.num_attention_heads = num_attention_heads + self.mlp_dim = mlp_dim + self.attention_downsample_rate = attention_downsample_rate + + +class Sam2VideoConfig(PreTrainedConfig): + r""" + [`Sam2Config`] is the configuration class to store the configuration of a [`Sam2Model`]. It is used to instantiate a + SAM2 model according to the specified arguments, defining the memory attention, memory encoder, and image encoder + configs. Instantiating a configuration defaults will yield a similar configuration to that of the SAM 2.1 Hiera-tiny + [facebook/sam2.1-hiera-tiny](https://huggingface.co/facebook/sam2.1-hiera-tiny) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + vision_config (Union[`dict`, `Sam2VisionConfig`], *optional*): + Dictionary of configuration options used to initialize [`Sam2VisionConfig`]. + prompt_encoder_config (Union[`dict`, `Sam2PromptEncoderConfig`], *optional*): + Dictionary of configuration options used to initialize [`Sam2PromptEncoderConfig`]. + mask_decoder_config (Union[`dict`, `Sam2MaskDecoderConfig`], *optional*): + Dictionary of configuration options used to initialize [`Sam2MaskDecoderConfig`]. + initializer_range (`float`, *optional*, defaults to 0.02): + Standard deviation for parameter initialization. + num_maskmem (`int`, *optional*, defaults to 7): + The number of memory slots for the mask memory. + image_size (`int`, *optional*, defaults to 1024): + The size of the input images. + sigmoid_scale_for_mem_enc (`float`, *optional*, defaults to 20.0): + Scale factor for the sigmoid function in the memory encoder. + sigmoid_bias_for_mem_enc (`float`, *optional*, defaults to -10.0): + Bias for the sigmoid function in the memory encoder. + enable_occlusion_spatial_embedding (`bool`, *optional*, defaults to `True`): + Whether to enable spatial embedding for occlusions. + multimask_output_in_sam (`bool`, *optional*, defaults to `True`): + Whether to output multiple masks from the SAM head. + multimask_min_pt_num (`int`, *optional*, defaults to 0): + The minimum number of points to trigger multimask output. + multimask_max_pt_num (`int`, *optional*, defaults to 1): + The maximum number of points to trigger multimask output. + multimask_output_for_tracking (`bool`, *optional*, defaults to `True`): + Whether to use multimask output for tracking. + max_object_pointers_in_encoder (`int`, *optional*, defaults to 16): + The maximum number of object pointers in the encoder. + max_cond_frame_num (`int`, *optional*, defaults to -1): + Maximum number of conditioning frames to use in memory attention. Set to -1 to use all conditioning frames. + enable_temporal_pos_encoding_for_object_pointers (`bool`, *optional*, defaults to `True`): + Whether to enable temporal positional encoding for object pointers. + memory_attention_hidden_size (`int`, *optional*, defaults to 256): + Dimensionality of the memory attention hidden states. + memory_attention_num_layers (`int`, *optional*, defaults to 4): + The number of layers in the memory attention module. + memory_attention_num_attention_heads (`int`, *optional*, defaults to 1): + Number of attention heads for each attention layer in the memory attention. + memory_attention_downsample_rate (`int`, *optional*, defaults to 1): + The downsample rate for the attention layers. + memory_attention_feed_forward_hidden_size (`int`, *optional*, defaults to 2048): + The dimension of the feedforward network in the memory attention module. + memory_attention_feed_forward_hidden_act (`str`, *optional*, defaults to `"relu"`): + The non-linear activation function in the feedforward network in the memory attention module. + memory_attention_dropout (`float`, *optional*, defaults to 0.1): + The dropout rate for the memory attention module. + memory_attention_rope_theta (`float`, *optional*, defaults to 10000): + The Rope theta parameter. + memory_attention_rope_feat_sizes (`list[int]`, *optional*, defaults to `[64, 64]`): + The feature sizes for the Rope positional encoding. + memory_attention_rope_dropout (`float`, *optional*, defaults to 0.1): + The dropout rate for the Rope positional encoding. + memory_encoder_hidden_size (`int`, *optional*, defaults to 256): + Dimensionality of the memory encoder hidden states. + memory_encoder_output_channels (`int`, *optional*, defaults to 64): + The number of output channels for the memory encoder. + mask_downsampler_embed_dim (`int`, *optional*, defaults to 256): + The dimension of the mask downsampler embedding. + mask_downsampler_kernel_size (`int`, *optional*, defaults to 3): + The kernel size for the mask downsampler. + mask_downsampler_stride (`int`, *optional*, defaults to 2): + The stride for the mask downsampler. + mask_downsampler_padding (`int`, *optional*, defaults to 1): + The padding for the mask downsampler. + mask_downsampler_total_stride (`int`, *optional*, defaults to 16): + The total stride for the mask downsampler. + mask_downsampler_hidden_act (`str`, *optional*, defaults to `"gelu"`): + The non-linear activation function in the mask downsampler. + memory_fuser_num_layers (`int`, *optional*, defaults to 2): + The number of layers in the memory fuser. + memory_fuser_embed_dim (`int`, *optional*, defaults to 256): + The dimension of the embedding layer in the memory fuser. + memory_fuser_intermediate_dim (`int`, *optional*, defaults to 1024): + The dimension of the intermediate layer in the memory fuser. + memory_fuser_kernel_size (`int`, *optional*, defaults to 7): + The kernel size for the memory fuser. + memory_fuser_padding (`int`, *optional*, defaults to 3): + The padding for the memory fuser. + memory_fuser_layer_scale_init_value (`float`, *optional*, defaults to 1e-06): + The initial value for the layer scale in the memory fuser. + memory_fuser_hidden_act (`str`, *optional*, defaults to `"gelu"`): + The non-linear activation function in the memory fuser. + kwargs (*optional*): + Dictionary of keyword arguments. + + Example: + + ```python + >>> from transformers import ( + ... Sam2VisionConfig, + ... Sam2PromptEncoderConfig, + ... Sam2MaskDecoderConfig, + ... Sam2Model, + ... ) + + >>> # Initializing a Sam2Config with `"facebook/sam2.1_hiera_tiny"` style configuration + >>> configuration = Sam2config() + + >>> # Initializing a Sam2Model (with random weights) from the `"facebook/sam2.1_hiera_tiny"` style configuration + >>> model = Sam2Model(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + + >>> # We can also initialize a Sam2Config from a Sam2VisionConfig, Sam2PromptEncoderConfig, and Sam2MaskDecoderConfig + + >>> # Initializing SAM2 vision encoder, memory attention, and memory encoder configurations + >>> vision_config = Sam2VisionConfig() + >>> prompt_encoder_config = Sam2PromptEncoderConfig() + >>> mask_decoder_config = Sam2MaskDecoderConfig() + + >>> config = Sam2Config(vision_config, prompt_encoder_config, mask_decoder_config) + ```""" + + model_type = "sam2_video" + sub_configs = { + "vision_config": AutoConfig, + "prompt_encoder_config": Sam2VideoPromptEncoderConfig, + "mask_decoder_config": Sam2VideoMaskDecoderConfig, + } + + def __init__( + self, + vision_config=None, + prompt_encoder_config=None, + mask_decoder_config=None, + initializer_range=0.02, + num_maskmem=7, + image_size=1024, + sigmoid_scale_for_mem_enc=20.0, + sigmoid_bias_for_mem_enc=-10.0, + enable_occlusion_spatial_embedding=True, + multimask_output_in_sam=True, + multimask_min_pt_num=0, + multimask_max_pt_num=1, + multimask_output_for_tracking=True, + max_object_pointers_in_encoder=16, + max_cond_frame_num=-1, + enable_temporal_pos_encoding_for_object_pointers=True, + # memory attention + memory_attention_hidden_size=256, + memory_attention_num_layers=4, + memory_attention_num_attention_heads=1, + memory_attention_downsample_rate=1, + memory_attention_feed_forward_hidden_size=2048, + memory_attention_feed_forward_hidden_act="relu", + memory_attention_dropout=0.1, + memory_attention_rope_theta=10000, + memory_attention_rope_feat_sizes=None, + memory_attention_rope_dropout=0.1, + # memory encoder + memory_encoder_hidden_size=256, + memory_encoder_output_channels=64, + mask_downsampler_embed_dim=256, + mask_downsampler_kernel_size=3, + mask_downsampler_stride=2, + mask_downsampler_padding=1, + mask_downsampler_total_stride=16, + mask_downsampler_hidden_act="gelu", + memory_fuser_num_layers=2, + memory_fuser_embed_dim=256, + memory_fuser_intermediate_dim=1024, + memory_fuser_kernel_size=7, + memory_fuser_padding=3, + memory_fuser_layer_scale_init_value=1e-6, + memory_fuser_hidden_act="gelu", + **kwargs, + ): + super().__init__(**kwargs) + + vision_config = vision_config if vision_config is not None else {} + prompt_encoder_config = prompt_encoder_config if prompt_encoder_config is not None else {} + mask_decoder_config = mask_decoder_config if mask_decoder_config is not None else {} + memory_attention_rope_feat_sizes = ( + [64, 64] if memory_attention_rope_feat_sizes is None else memory_attention_rope_feat_sizes + ) + + if isinstance(vision_config, dict): + vision_config["model_type"] = vision_config.get("model_type", "sam2_vision_model") + vision_config = CONFIG_MAPPING[vision_config["model_type"]](**vision_config) + if isinstance(prompt_encoder_config, Sam2VideoPromptEncoderConfig): + prompt_encoder_config = prompt_encoder_config.to_dict() + if isinstance(mask_decoder_config, Sam2VideoMaskDecoderConfig): + mask_decoder_config = mask_decoder_config.to_dict() + + self.vision_config = vision_config + self.prompt_encoder_config = Sam2VideoPromptEncoderConfig(**prompt_encoder_config) + self.mask_decoder_config = Sam2VideoMaskDecoderConfig(**mask_decoder_config) + + self.initializer_range = initializer_range + self.num_maskmem = num_maskmem # default 1 input frame + 6 previous frames + self.image_size = image_size + self.sigmoid_scale_for_mem_enc = sigmoid_scale_for_mem_enc + self.sigmoid_bias_for_mem_enc = sigmoid_bias_for_mem_enc + self.multimask_output_in_sam = multimask_output_in_sam + self.multimask_min_pt_num = multimask_min_pt_num + self.multimask_max_pt_num = multimask_max_pt_num + self.multimask_output_for_tracking = multimask_output_for_tracking + self.max_object_pointers_in_encoder = max_object_pointers_in_encoder + self.max_cond_frame_num = max_cond_frame_num + # The next 4 are True for sam2.1 and False for sam2 + self.enable_occlusion_spatial_embedding = enable_occlusion_spatial_embedding + self.enable_temporal_pos_encoding_for_object_pointers = enable_temporal_pos_encoding_for_object_pointers + + # memory attention + self.memory_attention_hidden_size = memory_attention_hidden_size + self.memory_attention_num_layers = memory_attention_num_layers + self.memory_attention_num_attention_heads = memory_attention_num_attention_heads + self.memory_attention_downsample_rate = memory_attention_downsample_rate + self.memory_attention_feed_forward_hidden_size = memory_attention_feed_forward_hidden_size + self.memory_attention_feed_forward_hidden_act = memory_attention_feed_forward_hidden_act + self.memory_attention_dropout = memory_attention_dropout + self.memory_attention_rope_theta = memory_attention_rope_theta + self.memory_attention_rope_feat_sizes = memory_attention_rope_feat_sizes + self.memory_attention_rope_dropout = memory_attention_rope_dropout + + # memory encoder + self.memory_encoder_hidden_size = memory_encoder_hidden_size + self.memory_encoder_output_channels = memory_encoder_output_channels + self.mask_downsampler_embed_dim = mask_downsampler_embed_dim + self.mask_downsampler_kernel_size = mask_downsampler_kernel_size + self.mask_downsampler_stride = mask_downsampler_stride + self.mask_downsampler_padding = mask_downsampler_padding + self.mask_downsampler_total_stride = mask_downsampler_total_stride + self.mask_downsampler_hidden_act = mask_downsampler_hidden_act + self.memory_fuser_num_layers = memory_fuser_num_layers + self.memory_fuser_embed_dim = memory_fuser_embed_dim + self.memory_fuser_intermediate_dim = memory_fuser_intermediate_dim + self.memory_fuser_kernel_size = memory_fuser_kernel_size + self.memory_fuser_padding = memory_fuser_padding + self.memory_fuser_layer_scale_init_value = memory_fuser_layer_scale_init_value + self.memory_fuser_hidden_act = memory_fuser_hidden_act + + +__all__ = ["Sam2VideoMaskDecoderConfig", "Sam2VideoPromptEncoderConfig", "Sam2VideoConfig"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam2_video/modeling_sam2_video.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam2_video/modeling_sam2_video.py new file mode 100644 index 0000000000000000000000000000000000000000..0f20ca5c75dcda592bb0c8d1ab03e5155b4e6d0f --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam2_video/modeling_sam2_video.py @@ -0,0 +1,2795 @@ +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# This file was automatically generated from src/transformers/models/sam2_video/modular_sam2_video.py. +# Do NOT edit this file manually as any edits will be overwritten by the generation of +# the file from the modular. If any change should be done, please apply the change to the +# modular_sam2_video.py file directly. One of our CI enforces this. +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# Copyright 2025 The Meta AI Authors and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import math +from collections import OrderedDict +from collections.abc import Callable, Iterator +from dataclasses import dataclass +from typing import Any + +import numpy as np +import torch +import torch.nn as nn +import torch.nn.functional as F +from torch import Tensor +from tqdm import tqdm + +from ... import initialization as init +from ...activations import ACT2FN +from ...modeling_flash_attention_utils import FlashAttentionKwargs +from ...modeling_layers import GradientCheckpointingLayer +from ...modeling_outputs import BaseModelOutput, BaseModelOutputWithPooling +from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel +from ...processing_utils import Unpack +from ...pytorch_utils import compile_compatible_method_lru_cache +from ...utils import ModelOutput, auto_docstring, can_return_tuple, logging +from ...utils.generic import TransformersKwargs, is_flash_attention_requested +from ...utils.output_capturing import OutputRecorder +from ..auto import AutoModel +from .configuration_sam2_video import Sam2VideoConfig, Sam2VideoMaskDecoderConfig, Sam2VideoPromptEncoderConfig + + +logger = logging.get_logger(__name__) + + +class Sam2VideoInferenceCache: + """Cache for vision features and model constants.""" + + def __init__( + self, + inference_device: torch.device | str = "cpu", + inference_state_device: torch.device | str = "cpu", + max_vision_features_cache_size: int = 1, + ): + self.inference_device = inference_device + self.inference_state_device = inference_state_device + self.max_vision_features_cache_size = max_vision_features_cache_size + + self._vision_features = {} + + def cache_vision_features(self, frame_idx: int, features: dict): + """Cache vision features with automatic device management.""" + cached = {} + if len(self._vision_features) >= self.max_vision_features_cache_size: + # remove the oldest frame + self._vision_features.pop(min(self._vision_features.keys())) + + for key, value in features.items(): + if isinstance(value, torch.Tensor): + cached[key] = value.to(self.inference_state_device, non_blocking=True) + elif isinstance(value, (list, tuple)) and value and isinstance(value[0], torch.Tensor): + cached[key] = [v.to(self.inference_state_device, non_blocking=True) for v in value] + else: + cached[key] = value + self._vision_features[frame_idx] = cached + + def get_vision_features(self, frame_idx: int) -> dict | None: + """Get cached vision features, automatically moved to inference device.""" + if frame_idx not in self._vision_features: + return None + + cached = self._vision_features[frame_idx] + moved = {} + for key, value in cached.items(): + if isinstance(value, torch.Tensor): + moved[key] = value.to(self.inference_device, non_blocking=True) + elif isinstance(value, (list, tuple)) and value and isinstance(value[0], torch.Tensor): + moved[key] = [v.to(self.inference_device, non_blocking=True) for v in value] + else: + moved[key] = value + return moved + + def clear_all(self): + """Clear all cached data.""" + self._vision_features.clear() + + +class Sam2VideoInferenceSession: + r""" + Manages video inference session parameters, state and cache. + + Args: + video (`torch.FloatTensor`, *optional*): + The video to process. No need to provide when streaming. + video_height (`int`, *optional*): + The height of the video. + video_width (`int`, *optional*): + The width of the video. + inference_device (`torch.device`, *optional*, defaults to `"cpu"`): + The device to use for inference. + inference_state_device (`torch.device`, *optional*, defaults to `"cpu"`): + The device to store the inference state on. + video_storage_device (`torch.device`, *optional*, defaults to `"cpu"`): + The device to store the video on. + dtype (`torch.dtype`, *optional*, defaults to `"float32"`): + The dtype to use for the video. + max_vision_features_cache_size (`int`, *optional*, defaults to 1): + The maximum number of vision features to cache. + """ + + def __init__( + self, + video: torch.FloatTensor | None = None, + video_height: int | None = None, + video_width: int | None = None, + inference_device: torch.device | str = "cpu", + inference_state_device: torch.device | str = "cpu", + video_storage_device: torch.device | str = "cpu", + dtype: torch.dtype | str = "float32", + max_vision_features_cache_size: int = 1, + ): + # store as a dictionary to avoid double memory allocation with torch.cat when adding new frames + self.processed_frames = ( + dict(enumerate(video.to(video_storage_device, dtype=dtype))) if video is not None else None + ) + self.video_height = video_height + self.video_width = video_width + + self.inference_device = inference_device + self.inference_state_device = inference_state_device + self.video_storage_device = video_storage_device + self.dtype = dtype + self.max_vision_features_cache_size = max_vision_features_cache_size + + # Cache for computed features + self.cache = Sam2VideoInferenceCache( + inference_device=self.inference_device, + inference_state_device=self.inference_state_device, + max_vision_features_cache_size=self.max_vision_features_cache_size, + ) + + # Persistent object tracking state + self._obj_id_to_idx = OrderedDict() + self._obj_idx_to_id = OrderedDict() + self.obj_ids = [] + + # Persistent user inputs + self.point_inputs_per_obj = {} + self.mask_inputs_per_obj = {} + + # Persistent model outputs/history + self.output_dict_per_obj = {} + self.frames_tracked_per_obj = {} + + # Session state flags + self.obj_with_new_inputs = [] + + @property + def num_frames(self) -> int | None: + return len(self.processed_frames) if self.processed_frames is not None else None + + # Object management + def obj_id_to_idx(self, obj_id: int) -> int: + """Map object ID to index, creating new entry if needed.""" + obj_idx = self._obj_id_to_idx.get(obj_id, None) + if obj_idx is not None: + return obj_idx + + obj_idx = len(self._obj_id_to_idx) + self._obj_id_to_idx[obj_id] = obj_idx + self._obj_idx_to_id[obj_idx] = obj_id + self.obj_ids = list(self._obj_id_to_idx) + + self.point_inputs_per_obj[obj_idx] = {} + self.mask_inputs_per_obj[obj_idx] = {} + self.output_dict_per_obj[obj_idx] = { + "cond_frame_outputs": {}, + "non_cond_frame_outputs": {}, + } + self.frames_tracked_per_obj[obj_idx] = {} + + return obj_idx + + # Video Inference specific functions + def obj_idx_to_id(self, obj_idx: int) -> int: + """Map model-side object index to client-side object id.""" + return self._obj_idx_to_id[obj_idx] + + def get_obj_num(self) -> int: + """Get the total number of unique object ids received so far in this session.""" + return len(self._obj_idx_to_id) + + # Input management with device handling + def add_point_inputs(self, obj_idx: int, frame_idx: int, inputs: dict): + """Add point inputs with automatic device placement.""" + device_inputs = {} + for key, value in inputs.items(): + if isinstance(value, torch.Tensor): + device_inputs[key] = value.to(self.inference_device, non_blocking=False) + else: + device_inputs[key] = value + self.point_inputs_per_obj[obj_idx][frame_idx] = device_inputs + + def remove_point_inputs(self, obj_idx: int, frame_idx: int): + """Remove point inputs.""" + self.point_inputs_per_obj[obj_idx].pop(frame_idx, None) + + def add_mask_inputs(self, obj_idx: int, frame_idx: int, inputs: torch.Tensor): + """Add mask inputs with automatic device placement.""" + self.mask_inputs_per_obj[obj_idx][frame_idx] = inputs.to( + self.inference_device, dtype=self.dtype, non_blocking=True + ) + + def remove_mask_inputs(self, obj_idx: int, frame_idx: int): + """Remove mask inputs.""" + self.mask_inputs_per_obj[obj_idx].pop(frame_idx, None) + + # Output management with smart device placement + def store_output( + self, + obj_idx: int, + frame_idx: int, + output_key: str | None = None, + output_value: torch.Tensor | dict | None = None, + is_conditioning_frame: bool = True, + ): + """ + Store output with smart device management. + If output_key is None, the output is stored as a dictionary. + + Args: + obj_idx (int): The index of the object. + frame_idx (int): The index of the frame. + output_key (Optional[str]): The key of the output. If None, the output is stored as a dictionary. + output_value (Optional[Union[torch.Tensor, dict]]): The value of the output. + is_conditioning_frame (bool): Whether the output is for a conditioning frame. + """ + storage_key = "cond_frame_outputs" if is_conditioning_frame else "non_cond_frame_outputs" + + if output_key is None and isinstance(output_value, dict): + self.output_dict_per_obj[obj_idx][storage_key][frame_idx] = {} + for key, value in output_value.items(): + self.store_output(obj_idx, frame_idx, key, value, is_conditioning_frame) + return + + # Device placement: small tensors stay on inference device, large ones go to inference state device + if output_key in ["object_pointer", "object_score_logits"]: # Small tensors + self.output_dict_per_obj[obj_idx][storage_key][frame_idx][output_key] = output_value + elif isinstance(output_value, torch.Tensor): # Large tensors like masks, features + self.output_dict_per_obj[obj_idx][storage_key][frame_idx][output_key] = output_value.to( + self.inference_state_device, non_blocking=True + ) + else: + self.output_dict_per_obj[obj_idx][storage_key][frame_idx][output_key] = output_value + + def get_output( + self, + obj_idx: int, + frame_idx: int, + output_key: str, + is_conditioning_frame: bool = True, + ): + """ + Get output with smart device management. + + Args: + obj_idx (int): The index of the object. + frame_idx (int): The index of the frame. + output_key (str): The key of the output. + is_conditioning_frame (bool): Whether the output is for a conditioning frame. + """ + storage_key = "cond_frame_outputs" if is_conditioning_frame else "non_cond_frame_outputs" + out = self.output_dict_per_obj[obj_idx][storage_key].get(frame_idx, None) + # move to inference device if needed + if out is None: + return None + value = out[output_key] + if isinstance(value, torch.Tensor): + value = value.to(self.inference_device, non_blocking=True) + return value + + # Video frame management + def add_new_frame(self, pixel_values: torch.Tensor, frame_idx: int | None = None) -> int: + """Add new frame with automatic device placement.""" + pixel_values = pixel_values.to(self.video_storage_device, dtype=self.dtype, non_blocking=True) + if pixel_values.dim() == 4: + pixel_values = pixel_values.squeeze(0) + + if frame_idx is None: + frame_idx = len(self.processed_frames) if self.processed_frames is not None else 0 + + if self.processed_frames is None: + self.processed_frames = {frame_idx: pixel_values} + else: + self.processed_frames[frame_idx] = pixel_values + + return frame_idx + + def get_frame(self, frame_idx: int) -> torch.Tensor: + """Get frame from video.""" + return self.processed_frames[frame_idx].to(self.inference_device, non_blocking=True) + + def reset_tracking_data(self): + """Reset tracking data but keep cache.""" + self._obj_id_to_idx.clear() + self._obj_idx_to_id.clear() + self.obj_ids.clear() + self.point_inputs_per_obj.clear() + self.mask_inputs_per_obj.clear() + self.output_dict_per_obj.clear() + self.frames_tracked_per_obj.clear() + self.obj_with_new_inputs = [] + # Note: cache and video data are preserved + + def reset_inference_session(self): + """Reset tracking data and cache.""" + self._obj_id_to_idx.clear() + self._obj_idx_to_id.clear() + self.obj_ids.clear() + self.point_inputs_per_obj.clear() + self.mask_inputs_per_obj.clear() + self.output_dict_per_obj.clear() + self.frames_tracked_per_obj.clear() + self.obj_with_new_inputs = [] + self.cache.clear_all() + + +class Sam2VideoLayerNorm(nn.LayerNorm): + r"""LayerNorm that supports two data formats: channels_last (default) or channels_first. + The ordering of the dimensions in the inputs. channels_last corresponds to inputs with shape (batch_size, height, + width, channels) while channels_first corresponds to inputs with shape (batch_size, channels, height, width). + """ + + def __init__(self, normalized_shape, *, eps=1e-6, data_format="channels_last", **kwargs): + super().__init__(normalized_shape, eps=eps, **kwargs) + if data_format not in ["channels_last", "channels_first"]: + raise NotImplementedError(f"Unsupported data format: {data_format}") + self.data_format = data_format + + def forward(self, features: torch.Tensor) -> torch.Tensor: + """ + Args: + features: Tensor of shape (batch_size, channels, height, width) OR (batch_size, height, width, channels) + """ + if self.data_format == "channels_first": + features = features.permute(0, 2, 3, 1) + features = super().forward(features) + features = features.permute(0, 3, 1, 2) + else: + features = super().forward(features) + return features + + +# copied and adapted from original implementation, also practically equal to DetrSinePositionEmbedding +class Sam2VideoPositionEmbeddingSine(nn.Module): + """ + This is a more standard version of the position embedding, very similar to the one used by the Attention is all you + need paper, generalized to work on images. + """ + + def __init__( + self, num_pos_feats: int = 64, temperature: int = 10000, normalize: bool = False, scale: float | None = None + ): + super().__init__() + if scale is not None and normalize is False: + raise ValueError("normalize should be True if scale is passed") + self.num_pos_feats = num_pos_feats + self.temperature = temperature + self.normalize = normalize + self.scale = 2 * math.pi if scale is None else scale + + @compile_compatible_method_lru_cache(maxsize=1) + def forward( + self, + shape: torch.Size, + device: torch.device | str, + dtype: torch.dtype, + mask: Tensor | None = None, + ) -> Tensor: + if mask is None: + mask = torch.zeros((shape[0], shape[2], shape[3]), device=device, dtype=torch.bool) + not_mask = (~mask).to(dtype) + y_embed = not_mask.cumsum(1) + x_embed = not_mask.cumsum(2) + if self.normalize: + eps = 1e-6 + y_embed = y_embed / (y_embed[:, -1:, :] + eps) * self.scale + x_embed = x_embed / (x_embed[:, :, -1:] + eps) * self.scale + + dim_t = torch.arange(self.num_pos_feats, dtype=torch.int64, device=device).to(dtype) + dim_t = self.temperature ** (2 * torch.div(dim_t, 2, rounding_mode="floor") / self.num_pos_feats) + + pos_x = x_embed[:, :, :, None] / dim_t + pos_y = y_embed[:, :, :, None] / dim_t + pos_x = torch.stack((pos_x[:, :, :, 0::2].sin(), pos_x[:, :, :, 1::2].cos()), dim=4).flatten(3) + pos_y = torch.stack((pos_y[:, :, :, 0::2].sin(), pos_y[:, :, :, 1::2].cos()), dim=4).flatten(3) + pos = torch.cat((pos_y, pos_x), dim=3).permute(0, 3, 1, 2) + return pos + + +def eager_attention_forward( + module: nn.Module, + query: torch.Tensor, + key: torch.Tensor, + value: torch.Tensor, + attention_mask: torch.Tensor | None, + scaling: float, + dropout: float = 0.0, + **kwargs, +): + attn_weights = torch.matmul(query, key.transpose(2, 3)) * scaling + if attention_mask is not None: + attn_weights = attn_weights + attention_mask + + attn_weights = nn.functional.softmax(attn_weights, dim=-1, dtype=torch.float32).to(query.dtype) + attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training) + attn_output = torch.matmul(attn_weights, value) + attn_output = attn_output.transpose(1, 2).contiguous() + + return attn_output, attn_weights + + +class Sam2VideoAttention(nn.Module): + """ + SAM2_VIDEO's attention layer that allows for downscaling the size of the embedding after projection to queries, keys, and + values. + """ + + def __init__(self, config, downsample_rate=None): + super().__init__() + downsample_rate = config.attention_downsample_rate if downsample_rate is None else downsample_rate + self.config = config + self.hidden_size = config.hidden_size + self.internal_dim = config.hidden_size // downsample_rate + self.num_attention_heads = config.num_attention_heads + self.head_dim = self.internal_dim // config.num_attention_heads + self.scaling = self.head_dim**-0.5 + self.is_causal = False + + self.q_proj = nn.Linear(self.hidden_size, self.internal_dim) + self.k_proj = nn.Linear(self.hidden_size, self.internal_dim) + self.v_proj = nn.Linear(self.hidden_size, self.internal_dim) + self.o_proj = nn.Linear(self.internal_dim, self.hidden_size) + + def forward( + self, + query: torch.Tensor, + key: torch.Tensor, + value: torch.Tensor, + attention_similarity: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor, torch.Tensor]: + # Input projections + batch_size, point_batch_size = query.shape[:2] + new_shape = (batch_size * point_batch_size, -1, self.num_attention_heads, self.head_dim) + + query = self.q_proj(query).view(*new_shape).transpose(1, 2) + key = self.k_proj(key).view(*new_shape).transpose(1, 2) + value = self.v_proj(value).view(*new_shape).transpose(1, 2) + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, eager_attention_forward + ) + + if is_flash_attention_requested(self.config) and attention_similarity is not None: + # Target guided masks are represented as float masks and are incompatible with Flash Attention + # Fallback to SDPA for this call only so the rest of the model can still benefit from FA + attention_interface = ALL_ATTENTION_FUNCTIONS["sdpa"] + logger.warning_once( + "Falling back to SDPA for target-guided attention because " + "Flash Attention does not support additive bias masks." + ) + + attn_output, attn_weights = attention_interface( + self, + query, + key, + value, + attention_mask=attention_similarity, + dropout=0.0, + scaling=self.scaling, + is_causal=self.is_causal, + **kwargs, + ) + + attn_output = attn_output.reshape( + batch_size, point_batch_size, -1, self.num_attention_heads * self.head_dim + ).contiguous() + attn_output = self.o_proj(attn_output) + + return attn_output, attn_weights + + +class Sam2VideoTwoWayAttentionBlock(GradientCheckpointingLayer): + def __init__(self, config: Sam2VideoMaskDecoderConfig, skip_first_layer_pe: bool = False): + """ + A transformer block with four layers: + (1) self-attention of sparse inputs (2) cross attention of sparse inputs -> dense inputs (3) mlp block on + sparse inputs (4) cross attention of dense inputs -> sparse inputs + + Arguments: + config (`Sam2VideoMaskDecoderConfig`): + The configuration file used to instantiate the block + attention_downsample_rate (*optionalk*, int, defaults to 2): + The downsample ratio of the block used to reduce the inner dim of the attention. + skip_first_layer_pe (*optional*, bool, defaults to `False`): + Whether or not to skip the addition of the query_point_embedding on the first layer. + """ + super().__init__() + self.self_attn = Sam2VideoAttention(config, downsample_rate=1) + self.layer_norm1 = nn.LayerNorm(config.hidden_size) + + self.cross_attn_token_to_image = Sam2VideoAttention(config) + self.layer_norm2 = nn.LayerNorm(config.hidden_size) + + self.mlp = Sam2VideoFeedForward( + config.hidden_size, config.mlp_dim, config.hidden_size, num_layers=config.num_hidden_layers + ) + self.layer_norm3 = nn.LayerNorm(config.hidden_size) + + self.layer_norm4 = nn.LayerNorm(config.hidden_size) + self.cross_attn_image_to_token = Sam2VideoAttention(config) + + self.skip_first_layer_pe = skip_first_layer_pe + + def forward( + self, + queries: Tensor, + keys: Tensor, + query_point_embedding: Tensor, + key_point_embedding: Tensor, + attention_similarity: Tensor, + **kwargs: Unpack[TransformersKwargs], + ): + # Self attention block + if self.skip_first_layer_pe: + queries, _ = self.self_attn(query=queries, key=queries, value=queries) + else: + query = queries + query_point_embedding + attn_out, _ = self.self_attn(query=query, key=query, value=queries) + queries = queries + attn_out + queries = self.layer_norm1(queries) + + # Cross attention block, tokens attending to image embedding + query = queries + query_point_embedding + key = keys + key_point_embedding + + attn_out, _ = self.cross_attn_token_to_image( + query=query, key=key, value=keys, attention_similarity=attention_similarity + ) + queries = queries + attn_out + + queries = self.layer_norm2(queries) + + # MLP block + mlp_out = self.mlp(queries) + queries = queries + mlp_out + queries = self.layer_norm3(queries) + + # Cross attention block, image embedding attending to tokens + query = queries + query_point_embedding + key = keys + key_point_embedding + + attn_out, _ = self.cross_attn_image_to_token(query=key, key=query, value=queries) + keys = keys + attn_out + + keys = self.layer_norm4(keys) + return queries, keys, attn_out + + +class Sam2VideoFeedForward(nn.Module): + def __init__( + self, + input_dim: int, + hidden_dim: int, + output_dim: int, + num_layers: int, + activation: str = "relu", + sigmoid_output: bool = False, + ): + super().__init__() + self.num_layers = num_layers + self.activation = ACT2FN[activation] + self.proj_in = nn.Linear(input_dim, hidden_dim) + self.proj_out = nn.Linear(hidden_dim, output_dim) + self.layers = nn.ModuleList([nn.Linear(hidden_dim, hidden_dim) for _ in range(num_layers - 2)]) + self.sigmoid_output = sigmoid_output + + def forward(self, hidden_states): + hidden_states = self.proj_in(hidden_states) + hidden_states = self.activation(hidden_states) + for layer in self.layers: + hidden_states = self.activation(layer(hidden_states)) + + hidden_states = self.proj_out(hidden_states) + if self.sigmoid_output: + hidden_states = F.sigmoid(hidden_states) + return hidden_states + + +@dataclass +@auto_docstring(custom_intro="Base class for the Sam2Video model's output.") +class Sam2VideoImageSegmentationOutput(ModelOutput): + r""" + iou_scores (`torch.FloatTensor` of shape `(batch_size, point_batch_size, num_masks)`): + The Intersection over Union (IoU) scores of the predicted masks. + pred_masks (`torch.FloatTensor` of shape `(batch_size, point_batch_size, num_masks, height, width)`): + The predicted low-resolution masks. This is an alias for `low_res_masks`. These masks need to be post-processed + by the processor to be brought to the original image size. + object_score_logits (`torch.FloatTensor` of shape `(batch_size, point_batch_size, 1)`): + Logits for the object score, indicating if an object is present. + image_embeddings (`tuple(torch.FloatTensor)`): + The features from the FPN, which are used by the mask decoder. This is a tuple of `torch.FloatTensor` where each + tensor has shape `(batch_size, channels, height, width)`. + vision_hidden_states (`tuple(torch.FloatTensor)`, *optional*, returned when `output_hidden_states=True`): + Tuple of `torch.FloatTensor` (one for the output of each stage) of shape `(batch_size, height, width, hidden_size)`. + Hidden-states of the vision model at the output of each stage. + vision_attentions (`tuple(torch.FloatTensor)`, *optional*, returned when `output_attentions=True`): + Tuple of `torch.FloatTensor` (one for each layer) of shape `(batch_size, num_heads, sequence_length, sequence_length)`. + Attentions weights of the vision model. + mask_decoder_attentions (`tuple(torch.FloatTensor)`, *optional*, returned when `output_attentions=True`): + Tuple of `torch.FloatTensor` (one for each layer) of shape `(batch_size, num_heads, sequence_length, sequence_length)`. + Attentions weights of the mask decoder. + high_res_masks (`torch.FloatTensor` of shape `(batch_size, point_batch_size, num_masks, image_size, image_size)`, *optional*): + The predicted masks, upscaled to the original image size. Only used for Sam2VideoModel. + object_pointer (`torch.FloatTensor` of shape `(batch_size, point_batch_size, hidden_size)`, *optional*): + A tensor representing the object pointer, used for tracking in videos. Only used for Sam2VideoModel. + """ + + iou_scores: torch.FloatTensor | None = None + pred_masks: torch.FloatTensor | None = None + object_score_logits: torch.FloatTensor | None = None + image_embeddings: tuple[torch.FloatTensor, ...] = None + vision_hidden_states: tuple[torch.FloatTensor, ...] | None = None + vision_attentions: tuple[torch.FloatTensor, ...] | None = None + mask_decoder_attentions: tuple[torch.FloatTensor, ...] | None = None + + high_res_masks: torch.FloatTensor | None = None + object_pointer: torch.FloatTensor | None = None + + +@dataclass +@auto_docstring(custom_intro="Base class for the Sam2 model's output.") +class Sam2VideoSegmentationOutput(ModelOutput): + r""" + object_ids (`list[int]`, *optional*): + List of object IDs being tracked in the current frame. + pred_masks (`torch.FloatTensor` of shape `(batch_size, num_masks, height, width)`): + The predicted masks stored at the model's resolution. + object_score_logits (`torch.FloatTensor` of shape `(batch_size,)`, *optional*): + Logits for the object scores, indicating if objects are present. + frame_idx (`int`): + The frame index of the video. + """ + + object_ids: list[int] | None = None + pred_masks: torch.FloatTensor | None = None + object_score_logits: torch.FloatTensor | None = None + frame_idx: int | None = None + + +@auto_docstring +class Sam2VideoPreTrainedModel(PreTrainedModel): + config_class = Sam2VideoConfig + base_model_prefix = "sam2_video" + main_input_name = "pixel_values" + input_modalities = "video" + _supports_sdpa = True + _supports_flash_attn = True + _supports_attention_backend = True + + @torch.no_grad() + def _init_weights(self, module): + super()._init_weights(module) + if isinstance(module, Sam2VideoModel): + if module.no_memory_positional_encoding is not None: + init.zeros_(module.no_memory_positional_encoding) + if module.memory_temporal_positional_encoding is not None: + init.zeros_(module.memory_temporal_positional_encoding) + if module.no_object_pointer is not None: + init.zeros_(module.no_object_pointer) + if module.occlusion_spatial_embedding_parameter is not None: + init.zeros_(module.occlusion_spatial_embedding_parameter) + if isinstance(module, Sam2VideoMemoryFuserCXBlock): + if module.scale is not None: + init.zeros_(module.scale) + elif isinstance(module, Sam2VideoVisionRotaryEmbedding): + inv_freq = module.create_inv_freq() + init.copy_(module.rope_embeddings_cos, inv_freq.cos()) + init.copy_(module.rope_embeddings_sin, inv_freq.sin()) + elif isinstance(module, Sam2VideoPositionalEmbedding): + init.normal_(module.positional_embedding, std=module.scale) + + +class Sam2VideoVisionRotaryEmbedding(nn.Module): + """ + Vision Rotary Position Embedding for SAM2, following transformers library standards. + Supports 2D (axial) rotary embeddings for spatial dimensions. + """ + + def __init__(self, config: Sam2VideoConfig): + super().__init__() + self.dim = config.memory_attention_hidden_size // ( + config.memory_attention_downsample_rate * config.memory_attention_num_attention_heads + ) + # Ensure even dimension for proper axial splitting + if self.dim % 4 != 0: + raise ValueError("Dimension must be divisible by 4 for axial RoPE") + self.end_x, self.end_y = config.memory_attention_rope_feat_sizes + self.memory_attention_rope_theta = config.memory_attention_rope_theta + + # directly register the cos and sin embeddings as we have a fixed feature shape + inv_freq = self.create_inv_freq() + self.register_buffer("rope_embeddings_cos", inv_freq.cos(), persistent=False) + self.register_buffer("rope_embeddings_sin", inv_freq.sin(), persistent=False) + + @torch.no_grad() + def forward(self) -> tuple[torch.Tensor, torch.Tensor]: + # As the feature map size is fixed, we can just return the pre-computed embeddings. + return self.rope_embeddings_cos, self.rope_embeddings_sin + + def create_inv_freq(self): + freqs = 1.0 / ( + self.memory_attention_rope_theta ** (torch.arange(0, self.dim, 4)[: (self.dim // 4)].float() / self.dim) + ) + # Generate 2D position indices for axial rotary embedding + flattened_indices = torch.arange(self.end_x * self.end_y, dtype=torch.long) + x_positions = flattened_indices % self.end_x + y_positions = torch.div(flattened_indices, self.end_x, rounding_mode="floor") + freqs_x = torch.outer(x_positions, freqs).float() + freqs_y = torch.outer(y_positions, freqs).float() + inv_freq = torch.cat([freqs_x, freqs_y], dim=-1) + inv_freq = inv_freq.repeat_interleave(2, dim=-1) + return inv_freq + + +def rotate_pairwise(x): + """ + pairwise rotation of the hidden dims of the input. Differerent from Llama Half-Tensor Rotation. + + This is an optimized version of the following more explicit implementation: + ```python + x_rotated = torch.zeros_like(x, dtype=x.dtype, device=x.device) + x_rotated[..., ::2] = -x[..., 1::2] + x_rotated[..., 1::2] = x[..., ::2] + return x_rotated + ``` + """ + x = x.view(*x.shape[:-1], -1, 2) + x1, x2 = x.unbind(dim=-1) + x = torch.stack((-x2, x1), dim=-1) + return x.flatten(start_dim=-2) + + +# TODO: This leads to ~1e-07 max diff and ~1e-09 avg diff for q_embed and k_embed from the original implementation, most likely due to the use of complex tensors in the original implementation. +def apply_rotary_pos_emb_2d( + q: torch.Tensor, + k: torch.Tensor, + cos: torch.Tensor, + sin: torch.Tensor, + num_k_exclude_rope: int = 0, + repeat_freqs_k: bool = False, +) -> tuple[torch.Tensor, torch.Tensor]: + """ + Apply rotary position embedding to query and key tensors for vision models. + Follows the standard transformers library pattern. + + Args: + q: Query tensor of shape (..., seq_len, head_dim) + k: Key tensor of shape (..., seq_len, head_dim) + cos: Cosine position embedding of shape (seq_len, head_dim) + sin: Sine position embedding of shape (seq_len, head_dim) + repeat_freqs_k: Whether to repeat frequencies for keys (for cross-attention) + + Returns: + Rotated (q, k) tensors + """ + k_rot, k_pass = k[..., : k.shape[-2] - num_k_exclude_rope, :], k[..., k.shape[-2] - num_k_exclude_rope :, :] + q_embed = q.float() # force upscale to float32 as in the original implementation + q_embed = (q_embed * cos) + (rotate_pairwise(q_embed) * sin) + if k_rot.shape[-2] == 0: + # Handle case where keys might be empty due to dropout + return q_embed.type_as(q), torch.cat([k_rot, k_pass], dim=-2) + + # Handle key tensor - may need to repeat frequencies if different sequence length + if repeat_freqs_k and k_rot.shape[-2] != q.shape[-2]: + # Repeat cos/sin to match key sequence length + repeat_factor = k_rot.shape[-2] // q.shape[-2] + cos_k = cos.repeat(1, 1, repeat_factor, 1) + sin_k = sin.repeat(1, 1, repeat_factor, 1) + else: + cos_k = cos + sin_k = sin + + # Apply rotary embedding to keys + k_embed = k_rot.float() # force upscale to float32 as in the original implementation + k_embed = (k_embed * cos_k) + (rotate_pairwise(k_embed) * sin_k) + # Concatenate back to full shape + k_embed = torch.cat([k_embed.type_as(k), k_pass], dim=-2) + return q_embed.type_as(q), k_embed + + +class Sam2VideoRoPEAttention(nn.Module): + """Attention with rotary position encoding.""" + + def __init__( + self, + config: Sam2VideoConfig, + kv_in_dim: int | None = None, + rope_k_repeat=False, + ): + super().__init__() + self.config = config + self.hidden_size = config.memory_attention_hidden_size + self.internal_dim = self.hidden_size // config.memory_attention_downsample_rate + self.num_attention_heads = config.memory_attention_num_attention_heads + self.head_dim = self.internal_dim // config.memory_attention_num_attention_heads + self.scaling = self.head_dim**-0.5 + self.is_causal = False + + self.kv_in_dim = kv_in_dim if kv_in_dim is not None else self.hidden_size + + self.q_proj = nn.Linear(self.hidden_size, self.internal_dim) + self.k_proj = nn.Linear(self.kv_in_dim, self.internal_dim) + self.v_proj = nn.Linear(self.kv_in_dim, self.internal_dim) + self.o_proj = nn.Linear(self.internal_dim, self.hidden_size) + + self.rope_k_repeat = rope_k_repeat + self.dropout_p = config.memory_attention_rope_dropout + + def forward( + self, + query: torch.Tensor, + key: torch.Tensor, + value: torch.Tensor, + position_embeddings: tuple[torch.Tensor, torch.Tensor], + num_k_exclude_rope: int = 0, + **kwargs: Unpack[FlashAttentionKwargs], + ) -> Tensor: + # Input projections + batch_size, point_batch_size = query.shape[:2] + new_shape = (batch_size * point_batch_size, -1, self.num_attention_heads, self.head_dim) + + query = self.q_proj(query).view(*new_shape).transpose(1, 2) + key = self.k_proj(key).view(*new_shape).transpose(1, 2) + value = self.v_proj(value).view(*new_shape).transpose(1, 2) + + cos, sin = position_embeddings + # Apply rotary position encoding, excluding some keys if specified + query, key = apply_rotary_pos_emb_2d( + query, key, cos, sin, repeat_freqs_k=self.rope_k_repeat, num_k_exclude_rope=num_k_exclude_rope + ) + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, eager_attention_forward + ) + + attn_output, attn_weights = attention_interface( + self, + query, + key, + value, + attention_mask=None, + dropout=0.0 if not self.training else self.dropout_p, + scaling=self.scaling, + is_causal=self.is_causal, + **kwargs, + ) + attn_output = attn_output.reshape( + batch_size, point_batch_size, -1, self.num_attention_heads * self.head_dim + ).contiguous() + attn_output = self.o_proj(attn_output) + return attn_output, attn_weights + + +class Sam2VideoMemoryAttentionLayer(nn.Module): + def __init__(self, config: Sam2VideoConfig): + super().__init__() + hidden_size = config.memory_attention_hidden_size + self.self_attn = Sam2VideoRoPEAttention(config) + self.cross_attn_image = Sam2VideoRoPEAttention(config, kv_in_dim=64, rope_k_repeat=True) + + # Implementation of Feedforward model + self.linear1 = nn.Linear(hidden_size, config.memory_attention_feed_forward_hidden_size) + self.dropout = nn.Dropout(config.memory_attention_dropout) + self.linear2 = nn.Linear(config.memory_attention_feed_forward_hidden_size, hidden_size) + + self.layer_norm1 = nn.LayerNorm(hidden_size) + self.layer_norm2 = nn.LayerNorm(hidden_size) + self.layer_norm3 = nn.LayerNorm(hidden_size) + self.dropout1 = nn.Dropout(config.memory_attention_dropout) + self.dropout2 = nn.Dropout(config.memory_attention_dropout) + self.dropout3 = nn.Dropout(config.memory_attention_dropout) + + self.activation = ACT2FN[config.memory_attention_feed_forward_hidden_act] + + def forward( + self, + queries: Tensor, + keys: Tensor, + key_point_embedding: Tensor, + rope_position_embeddings: tuple[Tensor, Tensor], + num_k_exclude_rope: int = 0, + ) -> torch.Tensor: + # Self-Attention + query = self.layer_norm1(queries) + query, _ = self.self_attn(query=query, key=query, value=query, position_embeddings=rope_position_embeddings) + queries = queries + self.dropout1(query) + + # Cross-Attention + query = self.layer_norm2(queries) + query, _ = self.cross_attn_image( + query=query, + key=keys + key_point_embedding, + value=keys, + position_embeddings=rope_position_embeddings, + num_k_exclude_rope=num_k_exclude_rope, + ) + queries = queries + self.dropout2(query) + # MLP + query = self.layer_norm3(queries) + query = self.linear2(self.dropout(self.activation(self.linear1(query)))) + queries = queries + self.dropout3(query) + return queries + + +class Sam2VideoMemoryAttention(nn.Module): + def __init__(self, config: Sam2VideoConfig): + super().__init__() + self.layers = nn.ModuleList( + [Sam2VideoMemoryAttentionLayer(config) for _ in range(config.memory_attention_num_layers)] + ) + self.layer_norm = nn.LayerNorm(config.memory_attention_hidden_size) + self.rotary_emb = Sam2VideoVisionRotaryEmbedding(config=config) + + def forward( + self, + current_vision_features: torch.Tensor, + memory: torch.Tensor, + current_vision_position_embeddings: Tensor | None = None, + memory_posision_embeddings: Tensor | None = None, + num_object_pointer_tokens: int = 0, + ): + """ + Args: + current_vision_features (`torch.FloatTensor`): + The current vision features used for self-attention. + memory (`torch.FloatTensor`): + The memory features used for cross-attention. + current_vision_position_embeddings (`torch.FloatTensor`, *optional*): + The position embeddings for the current vision features. + memory_posision_embeddings (`torch.FloatTensor`, *optional*): + The position embeddings for the memory features. + num_object_pointer_tokens (`int`, *optional*, defaults to 0): + The number of object pointer tokens. + """ + output = current_vision_features + if current_vision_position_embeddings is not None: + output = output + 0.1 * current_vision_position_embeddings + + # Convert to batch first + output = output.transpose(0, 1) + memory = memory.transpose(0, 1).unsqueeze(1) + memory_posision_embeddings = memory_posision_embeddings.transpose(0, 1).unsqueeze(1) + rope_position_embeddings = self.rotary_emb() + for layer in self.layers: + output = layer( + queries=output.unsqueeze(1) if output.ndim == 3 else output, + keys=memory, + key_point_embedding=memory_posision_embeddings, + rope_position_embeddings=rope_position_embeddings, + num_k_exclude_rope=num_object_pointer_tokens, + ) + + normed_output = self.layer_norm(output) + + # Convert back to seq first + normed_output = normed_output.transpose(0, 1) + + return normed_output + + +# Lightly adapted from ConvNext (https://github.com/facebookresearch/ConvNeXt) +class Sam2VideoMemoryFuserCXBlock(GradientCheckpointingLayer): + def __init__(self, config: Sam2VideoConfig): + super().__init__() + self.depthwise_conv = nn.Conv2d( + config.memory_fuser_embed_dim, + config.memory_fuser_embed_dim, + kernel_size=config.memory_fuser_kernel_size, + padding=config.memory_fuser_padding, + groups=config.memory_fuser_embed_dim, + ) # depthwise conv + self.layer_norm = Sam2VideoLayerNorm(config.memory_fuser_embed_dim, eps=1e-6, data_format="channels_first") + self.activation = ACT2FN[config.memory_fuser_hidden_act] + self.pointwise_conv1 = nn.Linear( + config.memory_fuser_embed_dim, config.memory_fuser_intermediate_dim + ) # pointwise/1x1 convs, implemented with linear layers + self.pointwise_conv2 = nn.Linear(config.memory_fuser_intermediate_dim, config.memory_fuser_embed_dim) + self.scale = nn.Parameter( + config.memory_fuser_layer_scale_init_value * torch.ones(config.memory_fuser_embed_dim), + requires_grad=True, + ) + + def forward(self, hidden_states): + input = hidden_states + hidden_states = self.depthwise_conv(hidden_states) + hidden_states = self.layer_norm(hidden_states) + hidden_states = hidden_states.permute(0, 2, 3, 1) # (N, C, H, W) -> (N, H, W, C) + hidden_states = self.pointwise_conv1(hidden_states) + hidden_states = self.activation(hidden_states) + hidden_states = self.pointwise_conv2(hidden_states) + hidden_states = self.scale * hidden_states + hidden_states = hidden_states.permute(0, 3, 1, 2) # (N, H, W, C) -> (N, C, H, W) + + hidden_states = input + hidden_states + return hidden_states + + +class Sam2VideoMemoryFuser(nn.Module): + def __init__(self, config: Sam2VideoConfig): + super().__init__() + self.layers = nn.ModuleList( + [Sam2VideoMemoryFuserCXBlock(config) for _ in range(config.memory_fuser_num_layers)] + ) + + def forward(self, hidden_states): + # normally hidden_states: (N, C, H, W) + for layer in self.layers: + hidden_states = layer(hidden_states) + return hidden_states + + +class Sam2VideoMaskDownSamplerLayer(nn.Module): + def __init__(self, config: Sam2VideoConfig, in_channels: int, out_channels: int): + super().__init__() + self.conv = nn.Conv2d( + in_channels, + out_channels, + kernel_size=config.mask_downsampler_kernel_size, + stride=config.mask_downsampler_stride, + padding=config.mask_downsampler_padding, + ) + self.layer_norm = Sam2VideoLayerNorm(out_channels, eps=1e-6, data_format="channels_first") + self.activation = ACT2FN[config.mask_downsampler_hidden_act] + + def forward(self, x): + return self.activation(self.layer_norm(self.conv(x))) + + +class Sam2VideoMaskDownSampler(nn.Module): + """ + Progressively downsample a mask by total_stride, each time by stride. + Note that LayerNorm is applied per *token*, like in ViT. + + With each downsample (by a factor stride**2), channel capacity increases by the same factor. + In the end, we linearly project to embed_dim channels. + """ + + def __init__(self, config: Sam2VideoConfig): + super().__init__() + + num_layers = int(math.log2(config.mask_downsampler_total_stride) // math.log2(config.mask_downsampler_stride)) + + self.layers = nn.ModuleList() + self.activation = ACT2FN[config.mask_downsampler_hidden_act] + mask_in_chans, mask_out_chans = 1, 1 + for _ in range(num_layers): + mask_out_chans = mask_in_chans * (config.mask_downsampler_stride**2) + self.layers.append(Sam2VideoMaskDownSamplerLayer(config, mask_in_chans, mask_out_chans)) + mask_in_chans = mask_out_chans + + self.final_conv = nn.Conv2d(mask_out_chans, config.mask_downsampler_embed_dim, kernel_size=1) + + def forward(self, x): + for layer in self.layers: + x = layer(x) + x = self.final_conv(x) + return x + + +class Sam2VideoMemoryEncoder(nn.Module): + def __init__(self, config: Sam2VideoConfig): + super().__init__() + + hidden_size = config.memory_encoder_hidden_size + output_channels = config.memory_encoder_output_channels + self.mask_downsampler = Sam2VideoMaskDownSampler(config) + self.feature_projection = nn.Conv2d(hidden_size, hidden_size, kernel_size=1) + self.memory_fuser = Sam2VideoMemoryFuser(config) + self.position_encoding = Sam2VideoPositionEmbeddingSine(num_pos_feats=output_channels // 2, normalize=True) + self.projection = nn.Conv2d(hidden_size, output_channels, kernel_size=1) + + def forward( + self, + vision_features: torch.Tensor, + masks: torch.Tensor, + ) -> tuple[torch.Tensor, torch.Tensor]: + ## Process masks + masks = self.mask_downsampler(masks) + ## Fuse pixel_features and downsampled masks + + vision_features = self.feature_projection(vision_features) + vision_features = vision_features + masks + vision_features = self.memory_fuser(vision_features) + vision_features = self.projection(vision_features) + + vision_pos_enc = self.position_encoding(vision_features.shape, vision_features.device, vision_features.dtype) + + return vision_features, vision_pos_enc + + +class Sam2VideoPositionalEmbedding(nn.Module): + def __init__(self, config: Sam2VideoPromptEncoderConfig): + super().__init__() + self.scale = config.scale + positional_embedding = self.scale * torch.randn((2, config.hidden_size // 2)) + self.register_buffer("positional_embedding", positional_embedding) + + def forward(self, input_coords, input_shape=None): + """Positionally encode points that are normalized to [0,1].""" + coordinates = input_coords.clone() + + if input_shape is not None: + coordinates[:, :, :, 0] = coordinates[:, :, :, 0] / input_shape[1] + coordinates[:, :, :, 1] = coordinates[:, :, :, 1] / input_shape[0] + coordinates.to(torch.float32) + + # assuming coords are in [0, 1]^2 square and have d_1 x ... x d_n x 2 shape + coordinates = 2 * coordinates - 1 + coordinates = coordinates.to(self.positional_embedding.dtype) + coordinates = coordinates @ self.positional_embedding + coordinates = 2 * np.pi * coordinates + # outputs d_1 x ... x d_n x channel shape + return torch.cat([torch.sin(coordinates), torch.cos(coordinates)], dim=-1) + + +@dataclass +@auto_docstring(custom_intro="Base class for the vision encoder's outputs.") +class Sam2VideoVisionEncoderOutput(BaseModelOutputWithPooling): + r""" + last_hidden_state (`torch.FloatTensor` of shape `(batch_size, height, width, hidden_size)`): + Sequence of hidden-states at the output of the last layer of the model. + hidden_states (`tuple(torch.FloatTensor)`, *optional*, returned when `output_hidden_states=True` is passed or when `config.output_hidden_states=True`): + Tuple of `torch.FloatTensor` (one for the output of the embeddings, if the model has an embedding layer, + + one for the output of each stage) of shape `(batch_size, height, width, hidden_size)`. Hidden-states of the + model at the output of each stage. + attentions (`tuple(torch.FloatTensor)`, *optional*, returned when `output_attentions=True` is passed or when `config.output_attentions=True`): + Tuple of `torch.FloatTensor` (one for each layer) of shape `(batch_size, num_heads, sequence_length, + sequence_length)`. Attentions weights after the attention softmax, used to compute the weighted average in + the self-attention heads. + fpn_hidden_states (`tuple(torch.FloatTensor)`): + Tuple of `torch.FloatTensor` (one for each feature level, from high to low resolution) of shape + `(batch_size, hidden_size, height, width)`. Feature maps from the Feature Pyramid Network neck. + fpn_position_encoding (`tuple(torch.FloatTensor)`): + Tuple of `torch.FloatTensor` (one for each feature level, from high to low resolution) of shape + `(batch_size, hidden_size, height, width)`. Positional encodings corresponding to the `fpn_hidden_states`. + """ + + fpn_hidden_states: torch.FloatTensor | None = None + fpn_position_encoding: torch.FloatTensor | None = None + + +class Sam2VideoMaskEmbedding(nn.Module): + def __init__(self, config: Sam2VideoPromptEncoderConfig): + super().__init__() + self.mask_input_channels = config.mask_input_channels // 4 + self.activation = ACT2FN[config.hidden_act] + self.conv1 = nn.Conv2d(1, self.mask_input_channels, kernel_size=2, stride=2) + self.conv2 = nn.Conv2d(self.mask_input_channels, config.mask_input_channels, kernel_size=2, stride=2) + self.conv3 = nn.Conv2d(config.mask_input_channels, config.hidden_size, kernel_size=1) + self.layer_norm1 = Sam2VideoLayerNorm( + self.mask_input_channels, eps=config.layer_norm_eps, data_format="channels_first" + ) + self.layer_norm2 = Sam2VideoLayerNorm( + self.mask_input_channels * 4, eps=config.layer_norm_eps, data_format="channels_first" + ) + + def forward(self, masks): + hidden_states = self.conv1(masks) + hidden_states = self.layer_norm1(hidden_states) + hidden_states = self.activation(hidden_states) + + hidden_states = self.conv2(hidden_states) + hidden_states = self.layer_norm2(hidden_states) + hidden_states = self.activation(hidden_states) + dense_embeddings = self.conv3(hidden_states) + return dense_embeddings + + +class Sam2VideoPromptEncoder(nn.Module): + def __init__(self, config: Sam2VideoPromptEncoderConfig): + super().__init__() + self.shared_embedding = Sam2VideoPositionalEmbedding(config) + self.mask_embed = Sam2VideoMaskEmbedding(config) + self.no_mask_embed = nn.Embedding(1, config.hidden_size) + + self.image_embedding_size = (config.image_size // config.patch_size, config.image_size // config.patch_size) + self.mask_input_size = (4 * config.image_size // config.patch_size, 4 * config.image_size // config.patch_size) + self.input_image_size = config.image_size + + self.point_embed = nn.Embedding(config.num_point_embeddings, config.hidden_size) + self.hidden_size = config.hidden_size + self.not_a_point_embed = nn.Embedding(1, config.hidden_size) + + def _embed_points(self, points: torch.Tensor, labels: torch.Tensor, pad: bool) -> torch.Tensor: + """Embeds point prompts.""" + points = points + 0.5 # Shift to center of pixel + if pad: + points = torch.nn.functional.pad(points, (0, 0, 0, 1), mode="constant", value=0) + labels = torch.nn.functional.pad(labels, (0, 1), mode="constant", value=-1) + input_shape = (self.input_image_size, self.input_image_size) + point_embedding = self.shared_embedding(points, input_shape) + + # torch.where and expanding the labels tensor is required by the ONNX export + point_embedding = torch.where(labels[..., None] == -1, self.not_a_point_embed.weight, point_embedding) + + # This is required for the ONNX export. The dtype, device need to be explicitly + # specified as otherwise torch.onnx.export interprets as double + point_embedding = torch.where( + labels[..., None] != -10, + point_embedding, + torch.zeros_like(point_embedding), + ) + + # Add point embeddings for labels >= 0 + point_embedding = point_embedding + self.point_embed(labels.clamp(min=0)) * (labels >= 0).unsqueeze(-1) + + return point_embedding + + def _embed_boxes(self, boxes: torch.Tensor) -> torch.Tensor: + """Embeds box prompts.""" + boxes = boxes + 0.5 # Shift to center of pixel + coords = boxes.view(*boxes.shape[:2], 2, 2) + # add padding point for consistency with the original implementation + coords = torch.nn.functional.pad(coords, (0, 0, 0, 1), mode="constant", value=0) + corner_embedding = self.shared_embedding(coords, (self.input_image_size, self.input_image_size)) + corner_embedding[:, :, 0, :] += self.point_embed.weight[2] + corner_embedding[:, :, 1, :] += self.point_embed.weight[3] + corner_embedding[:, :, 2, :] = self.not_a_point_embed.weight.expand_as(corner_embedding[:, :, 2, :]) + return corner_embedding + + def forward( + self, + input_points: tuple[torch.Tensor, torch.Tensor] | None, + input_labels: torch.Tensor | None, + input_boxes: torch.Tensor | None, + input_masks: torch.Tensor | None, + ) -> tuple[torch.Tensor, torch.Tensor]: + """ + Embeds different types of prompts, returning both sparse and dense embeddings. + + Args: + points (`torch.Tensor`, *optional*): + point coordinates and labels to embed. + boxes (`torch.Tensor`, *optional*): + boxes to embed + masks (`torch.Tensor`, *optional*): + masks to embed + """ + sparse_embeddings = None + batch_size = 1 + if input_points is not None: + batch_size = input_points.shape[0] + if input_labels is None: + raise ValueError("If points are provided, labels must also be provided.") + point_embeddings = self._embed_points(input_points, input_labels, pad=(input_boxes is None)) + sparse_embeddings = point_embeddings + if input_boxes is not None: + batch_size = input_boxes.shape[0] + box_embeddings = self._embed_boxes(input_boxes) + if sparse_embeddings is None: + sparse_embeddings = box_embeddings + else: + sparse_embeddings = torch.cat([sparse_embeddings, box_embeddings], dim=2) + if input_masks is not None: + dense_embeddings = self.mask_embed(input_masks) + else: + dense_embeddings = self.no_mask_embed.weight.reshape(1, -1, 1, 1).expand( + batch_size, -1, self.image_embedding_size[0], self.image_embedding_size[1] + ) + + return sparse_embeddings, dense_embeddings + + +class Sam2VideoTwoWayTransformer(nn.Module): + def __init__(self, config: Sam2VideoMaskDecoderConfig): + super().__init__() + self.config = config + + self.num_hidden_layers = config.num_hidden_layers + self.layers = nn.ModuleList() + + for i in range(self.num_hidden_layers): + self.layers.append(Sam2VideoTwoWayAttentionBlock(config, skip_first_layer_pe=(i == 0))) + + self.final_attn_token_to_image = Sam2VideoAttention(config) + self.layer_norm_final_attn = nn.LayerNorm(config.hidden_size) + + def forward( + self, + point_embeddings: Tensor, + image_embeddings: Tensor, + image_positional_embeddings: Tensor, + attention_similarity: Tensor, + target_embedding=None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple | BaseModelOutput: + if image_embeddings is None: + raise ValueError("You have to specify an image_embedding") + + image_embeddings = image_embeddings.flatten(2).permute(0, 2, 1).unsqueeze(1) + image_positional_embeddings = image_positional_embeddings.flatten(2).permute(0, 2, 1).unsqueeze(1) + + # Prepare queries + queries = point_embeddings + keys = image_embeddings + + # Apply transformer blocks and final layernorm + for layer in self.layers: + if target_embedding is not None: + queries += target_embedding + + queries, keys, _ = layer( + queries=queries, + keys=keys, + query_point_embedding=point_embeddings, + key_point_embedding=image_positional_embeddings, + attention_similarity=attention_similarity, + **kwargs, + ) + # Apply the final attention layer from the points to the image + query = queries + point_embeddings + key = keys + image_positional_embeddings + + attn_out, _ = self.final_attn_token_to_image(query=query, key=key, value=keys) + + queries = queries + attn_out + queries = self.layer_norm_final_attn(queries) + return queries, keys + + +class Sam2VideoMaskDecoder(nn.Module): + def __init__(self, config: Sam2VideoMaskDecoderConfig): + super().__init__() + self.config = config + self.hidden_size = config.hidden_size + + self.num_multimask_outputs = config.num_multimask_outputs + self.num_mask_tokens = config.num_multimask_outputs + 1 + + self.iou_token = nn.Embedding(1, self.hidden_size) + self.mask_tokens = nn.Embedding(self.num_mask_tokens, self.hidden_size) + + self.transformer = Sam2VideoTwoWayTransformer(config) + + # should we create a new class for this? + self.upscale_conv1 = nn.ConvTranspose2d(self.hidden_size, self.hidden_size // 4, kernel_size=2, stride=2) + self.upscale_conv2 = nn.ConvTranspose2d(self.hidden_size // 4, self.hidden_size // 8, kernel_size=2, stride=2) + self.upscale_layer_norm = Sam2VideoLayerNorm(self.hidden_size // 4, data_format="channels_first") + self.activation = nn.GELU() + + mlps_list = [] + for _ in range(self.num_mask_tokens): + mlps_list += [Sam2VideoFeedForward(self.hidden_size, self.hidden_size, self.hidden_size // 8, 3)] + self.output_hypernetworks_mlps = nn.ModuleList(mlps_list) + self.iou_prediction_head = Sam2VideoFeedForward( + self.hidden_size, + config.iou_head_hidden_dim, + self.num_mask_tokens, + config.iou_head_depth, + sigmoid_output=True, + ) + + self.conv_s0 = nn.Conv2d(config.hidden_size, config.hidden_size // 8, kernel_size=1, stride=1) + self.conv_s1 = nn.Conv2d(config.hidden_size, config.hidden_size // 4, kernel_size=1, stride=1) + + self.obj_score_token = nn.Embedding(1, self.hidden_size) + self.pred_obj_score_head = Sam2VideoFeedForward(self.hidden_size, self.hidden_size, 1, 3) + + self.dynamic_multimask_via_stability = config.dynamic_multimask_via_stability + self.dynamic_multimask_stability_delta = config.dynamic_multimask_stability_delta + self.dynamic_multimask_stability_thresh = config.dynamic_multimask_stability_thresh + + def forward( + self, + image_embeddings: torch.Tensor, + image_positional_embeddings: torch.Tensor, + sparse_prompt_embeddings: torch.Tensor, + dense_prompt_embeddings: torch.Tensor, + multimask_output: bool, + high_resolution_features: list[torch.Tensor], + attention_similarity: torch.Tensor | None = None, + target_embedding: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor, torch.Tensor, torch.Tensor, torch.Tensor]: + """ + Predict masks given image and prompt embeddings. + + Args: + image_embeddings (`torch.Tensor`): + The embeddings from the image encoder. + image_positional_embeddings (`torch.Tensor`): + Positional encoding with the shape of image_embeddings. + sparse_prompt_embeddings (`torch.Tensor`): + The embeddings of the points and boxes. + dense_prompt_embeddings (`torch.Tensor`): + The embeddings of the mask inputs. + multimask_output (`bool`): + Whether to return multiple masks or a single mask. + high_resolution_features (`list[torch.Tensor]`, *optional*): + The high-resolution features from the vision encoder. + attention_similarity (`torch.Tensor`, *optional*): + The attention similarity tensor. + target_embedding (`torch.Tensor`, *optional*): + The target embedding. + """ + batch_size, num_channels, height, width = image_embeddings.shape + point_batch_size = sparse_prompt_embeddings.shape[1] + # Concatenate output tokens + output_tokens = torch.cat( + [ + self.obj_score_token.weight, + self.iou_token.weight, + self.mask_tokens.weight, + ], + dim=0, + ) + output_tokens = output_tokens.repeat(batch_size, point_batch_size, 1, 1) + + if sparse_prompt_embeddings.shape[0] != 0: + tokens = torch.cat((output_tokens, sparse_prompt_embeddings), dim=2) + else: + tokens = output_tokens + point_embeddings = tokens.to(self.iou_token.weight.dtype) + + # Expand per-image data in batch direction to be per-mask + image_embeddings = image_embeddings + dense_prompt_embeddings + image_embeddings = image_embeddings.repeat_interleave(point_batch_size, dim=0) + image_positional_embeddings = image_positional_embeddings.repeat_interleave(point_batch_size, 0) + # Run the transformer + point_embeddings, image_embeddings = self.transformer( + point_embeddings=point_embeddings, + image_embeddings=image_embeddings, + image_positional_embeddings=image_positional_embeddings, + attention_similarity=attention_similarity, + target_embedding=target_embedding, + **kwargs, + ) + iou_token_out = point_embeddings[:, :, 1, :] + mask_tokens_out = point_embeddings[:, :, 2 : (2 + self.num_mask_tokens), :] + + # Upscale mask embeddings and predict masks using the mask tokens + image_embeddings = image_embeddings.transpose(2, 3).view( + batch_size * point_batch_size, num_channels, height, width + ) + + feat_s0, feat_s1 = high_resolution_features + feat_s0 = feat_s0.repeat_interleave(point_batch_size, dim=0) + feat_s1 = feat_s1.repeat_interleave(point_batch_size, dim=0) + upscaled_embedding = self.upscale_conv1(image_embeddings) + feat_s1 + upscaled_embedding = self.activation(self.upscale_layer_norm(upscaled_embedding)) + upscaled_embedding = self.activation(self.upscale_conv2(upscaled_embedding) + feat_s0) + + hyper_in_list: list[torch.Tensor] = [] + for i in range(self.num_mask_tokens): + current_mlp = self.output_hypernetworks_mlps[i] + hyper_in_list += [current_mlp(mask_tokens_out[:, :, i, :])] + hyper_in = torch.stack(hyper_in_list, dim=2) + + _, num_channels, height, width = upscaled_embedding.shape + upscaled_embedding = upscaled_embedding.view(batch_size, point_batch_size, num_channels, height * width) + masks = (hyper_in @ upscaled_embedding).view(batch_size, point_batch_size, -1, height, width) + + # Generate mask quality predictions + iou_pred = self.iou_prediction_head(iou_token_out) + object_score_logits = self.pred_obj_score_head(point_embeddings[:, :, 0, :]) + + # Select the correct mask or masks for output + if multimask_output: + mask_slice = slice(1, None) + masks = masks[:, :, mask_slice, :, :] + iou_pred = iou_pred[:, :, mask_slice] + elif self.dynamic_multimask_via_stability and not self.training: + mask_slice = slice(0, 1) + masks, iou_pred = self._dynamic_multimask_via_stability(masks, iou_pred) + else: + mask_slice = slice(0, 1) + masks = masks[:, :, mask_slice, :, :] + iou_pred = iou_pred[:, :, mask_slice] + + sam_tokens_out = mask_tokens_out[:, :, mask_slice] # [b, 3, c] shape + + return masks, iou_pred, sam_tokens_out, object_score_logits + + def _get_stability_scores(self, mask_logits): + """ + Compute stability scores of the mask logits based on the IoU between upper and + lower thresholds. + """ + mask_logits = mask_logits.flatten(-2) + stability_delta = self.dynamic_multimask_stability_delta + area_i = torch.sum(mask_logits > stability_delta, dim=-1).float() + area_u = torch.sum(mask_logits > -stability_delta, dim=-1).float() + stability_scores = torch.where(area_u > 0, area_i / area_u, 1.0) + return stability_scores + + def _dynamic_multimask_via_stability(self, all_mask_logits, all_iou_scores): + """ + When outputting a single mask, if the stability score from the current single-mask + output (based on output token 0) falls below a threshold, we instead select from + multi-mask outputs (based on output token 1~3) the mask with the highest predicted + IoU score. This is intended to ensure a valid mask for both clicking and tracking. + """ + # The best mask from multimask output tokens (1~3) + multimask_logits = all_mask_logits[:, :, 1:, :, :] + multimask_iou_scores = all_iou_scores[:, :, 1:] + best_scores_inds = torch.argmax(multimask_iou_scores, dim=-1) # [B, P] + best_scores_inds_expanded = best_scores_inds.unsqueeze(-1).unsqueeze(-1).unsqueeze(-1) + best_scores_inds_expanded = best_scores_inds_expanded.expand( + -1, -1, 1, multimask_logits.size(-2), multimask_logits.size(-1) + ) + best_multimask_logits = torch.gather(multimask_logits, 2, best_scores_inds_expanded) # [B, P, 1, H, W] + best_multimask_iou_scores = torch.gather(multimask_iou_scores, 2, best_scores_inds.unsqueeze(-1)) # [B, P, 1] + + # The mask from singlemask output token 0 and its stability score + singlemask_logits = all_mask_logits[:, :, 0:1, :, :] + singlemask_iou_scores = all_iou_scores[:, :, 0:1] + stability_scores = self._get_stability_scores(singlemask_logits) + is_stable = stability_scores >= self.dynamic_multimask_stability_thresh + + # Dynamically fall back to best multimask output upon low stability scores. + mask_logits_out = torch.where( + is_stable[..., None, None].expand_as(singlemask_logits), + singlemask_logits, + best_multimask_logits, + ) + iou_scores_out = torch.where( + is_stable.expand_as(singlemask_iou_scores), + singlemask_iou_scores, + best_multimask_iou_scores, + ) + return mask_logits_out, iou_scores_out + + +# a large negative value as a placeholder score for missing objects +NO_OBJ_SCORE = -1024.0 + + +def get_1d_sine_pe(pos_inds, dim, temperature=10000): + """ + Get 1D sine positional embedding as in the original Transformer paper. + """ + pe_dim = dim // 2 + dim_t = torch.arange(pe_dim, dtype=torch.float32, device=pos_inds.device) + dim_t = temperature ** (2 * (dim_t // 2) / pe_dim) + + pos_embed = pos_inds.unsqueeze(-1) / dim_t + pos_embed = torch.cat([pos_embed.sin(), pos_embed.cos()], dim=-1) + return pos_embed + + +@auto_docstring +class Sam2VideoModel(Sam2VideoPreTrainedModel): + input_modalities = ("video", "text") + _can_record_outputs = {"mask_decoder_attentions": OutputRecorder(Sam2VideoTwoWayAttentionBlock, index=2)} + _tied_weights_keys = {} + _keys_to_ignore_on_load_unexpected = [] + + def __init__(self, config: Sam2VideoConfig): + super().__init__(config) + self.shared_image_embedding = Sam2VideoPositionalEmbedding(config.prompt_encoder_config) + self.vision_encoder = AutoModel.from_config(config.vision_config) + self.prompt_encoder = Sam2VideoPromptEncoder(config.prompt_encoder_config) + # The module using it is not a PreTrainedModel subclass so we need this + config.mask_decoder_config._attn_implementation = config._attn_implementation + self.mask_decoder = Sam2VideoMaskDecoder(config.mask_decoder_config) + + self.num_feature_levels = config.vision_config.num_feature_levels + self.backbone_feature_sizes = config.vision_config.backbone_feature_sizes + # a single token to indicate no memory embedding from previous frames + self.hidden_dim = config.vision_config.fpn_hidden_size + self.no_memory_embedding = torch.nn.Parameter(torch.zeros(1, 1, self.hidden_dim)) + self.config = config + # For video sequence inference + self.image_size = config.image_size + self.memory_attention = Sam2VideoMemoryAttention(config) + self.memory_encoder = Sam2VideoMemoryEncoder(config) + self.no_memory_positional_encoding = torch.nn.Parameter( + torch.zeros(1, 1, config.vision_config.fpn_hidden_size) + ) + self.mem_dim = config.memory_encoder_output_channels + self.num_maskmem = config.num_maskmem # Number of memories accessible + # Temporal encoding of the memories + self.memory_temporal_positional_encoding = torch.nn.Parameter( + torch.zeros(self.num_maskmem, 1, 1, self.mem_dim) + ) + + self.no_object_pointer = torch.nn.Parameter(torch.zeros(1, self.hidden_dim)) + # A conv layer to downsample the mask prompt to stride 4 (the same stride as + # low-res SAM mask logits) and to change its scales from 0~1 to SAM logit scale, + # so that it can be fed into the SAM mask decoder to generate a pointer. + self.mask_downsample = torch.nn.Conv2d(1, 1, kernel_size=4, stride=4) + # a feedforward layer on SAM output tokens to turn them into object pointers + self.object_pointer_proj = Sam2VideoFeedForward(self.hidden_dim, self.hidden_dim, self.hidden_dim, 3) + + if self.config.enable_temporal_pos_encoding_for_object_pointers: + # a linear projection on temporal positional encoding in object pointers to + # avoid potential interference with spatial positional encoding + self.temporal_positional_encoding_projection_layer = torch.nn.Linear(self.hidden_dim, self.mem_dim) + else: + self.temporal_positional_encoding_projection_layer = torch.nn.Identity() + + self.occlusion_spatial_embedding_parameter = None # compatibility with Sam2 + if config.enable_occlusion_spatial_embedding: + self.occlusion_spatial_embedding_parameter = torch.nn.Parameter(torch.zeros(1, self.mem_dim)) + + self.post_init() + + def get_input_embeddings(self): + return self.vision_encoder.get_input_embeddings() + + def get_image_wide_positional_embeddings(self) -> torch.Tensor: + size = self.prompt_encoder.image_embedding_size + target_device = self.shared_image_embedding.positional_embedding.device + target_dtype = self.shared_image_embedding.positional_embedding.dtype + grid = torch.ones(size, device=target_device, dtype=target_dtype) + y_embed = grid.cumsum(dim=0) - 0.5 + x_embed = grid.cumsum(dim=1) - 0.5 + y_embed = y_embed / size[0] + x_embed = x_embed / size[1] + + positional_embedding = self.shared_image_embedding(torch.stack([x_embed, y_embed], dim=-1)) + return positional_embedding.permute(2, 0, 1).unsqueeze(0) # channel x height x width + + @torch.no_grad() + def get_image_embeddings( + self, + pixel_values: torch.FloatTensor, + **kwargs: Unpack[TransformersKwargs], + ) -> list[torch.Tensor]: + r""" + Returns the image embeddings by passing the pixel values through the vision encoder. + + Args: + pixel_values (`torch.FloatTensor` of shape `(batch_size, num_channels, height, width)`): + Input pixel values + """ + batch_size = pixel_values.shape[0] + image_outputs = self.get_image_features(pixel_values, return_dict=True, **kwargs) + feature_maps = image_outputs.fpn_hidden_states + + # add no memory embedding to the last feature map + feature_maps[-1] = feature_maps[-1] + self.no_memory_embedding + + # reshape feature maps to the same shape as the backbone feature sizes + image_embeddings = [ + feat.permute(1, 2, 0).view(batch_size, -1, *feat_size) + for feat, feat_size in zip(feature_maps, self.backbone_feature_sizes) + ] + + return image_embeddings + + @torch.no_grad() + def get_prompt_embeddings( + self, + input_points: torch.FloatTensor | None = None, + input_labels: torch.LongTensor | None = None, + input_boxes: torch.FloatTensor | None = None, + input_masks: torch.LongTensor | None = None, + ) -> tuple[torch.Tensor, torch.Tensor]: + r""" + Returns the prompt embeddings by passing the input points, labels, boxes and masks through the prompt encoder. + + Args: + input_points (`torch.FloatTensor` of shape `(batch_size, point_batch_size, num_points_per_image, 2)`): + Optional input points for the prompt encoder. The padding of the point is automatically done by the + processor. `point_batch_size` refers to the number of masks that we want the model to predict per + point. The model will output `point_batch_size` times 3 masks in total. + input_labels (`torch.LongTensor` of shape `(batch_size, point_batch_size, num_points_per_image)`): + Optional input labels for the prompt encoder. The padding of the labels is automatically done by the + processor, or can be fed by the user. + input_boxes (`torch.FloatTensor` of shape `(batch_size, num_boxes_per_image, 4)`): + Optional input boxes for the prompt encoder. The padding of the boxes is automatically done by the + processor. users can also pass manually the input boxes. + input_masks (`torch.LongTensor` of shape `(batch_size, image_size, image_size)`): + Optional input masks for the prompt encoder. + """ + prompt_output = self.prompt_encoder( + input_points=input_points, + input_labels=input_labels, + input_boxes=input_boxes, + input_masks=input_masks, + ) + return prompt_output + + @torch.inference_mode() + @auto_docstring(custom_intro="Propagate the objects through a streamed video frame.") + def forward( + self, + inference_session: Sam2VideoInferenceSession, + frame_idx: int | None = None, + frame: torch.Tensor | None = None, + reverse: bool = False, + run_mem_encoder: bool = True, + **kwargs, + ) -> Sam2VideoSegmentationOutput: + r""" + inference_session (`Sam2VideoInferenceSession`): + The video inference session object. + frame_idx (`int`, *optional*): + The index of the frame on which to run inference. No need to provide when inferring + on a new streamed frame. + frame (`torch.Tensor`, *optional*): + The frame to process. Provide when streaming. + reverse (`bool`, *optional*, defaults to `False`): + Whether to propagate in reverse. + run_mem_encoder (`bool`, *optional*, defaults to `True`): + Whether to run the memory encoder on predicted masks. The memory encoder is batched across all objects for efficiency. + """ + if frame is not None: + frame_idx = inference_session.add_new_frame(frame, frame_idx) + + if frame is not None and inference_session.get_obj_num() == 0: + raise ValueError("No objects are provided for tracking; please add inputs first.") + + num_objects = inference_session.get_obj_num() + pred_masks_per_obj = [None] * num_objects + object_score_logits_per_obj = [None] * num_objects + + # Collect data for batched memory encoding + objects_needing_memory_encoding = [] + high_res_masks_for_memory = [] + object_score_logits_for_memory = [] + is_mask_from_pts_per_obj = [] + + # Note: We avoid batched inference here because per-object inputs (clicks/masks) + # can differ across objects. + for obj_idx in range(num_objects): + obj_id = inference_session.obj_idx_to_id(obj_idx) + has_new_inputs = obj_id in inference_session.obj_with_new_inputs + has_cond_output = frame_idx in inference_session.output_dict_per_obj[obj_idx]["cond_frame_outputs"] + # If this object has no new inputs and this frame already has a + # conditioning output, reuse the cached masks instead of recomputing. + if (not has_new_inputs) and has_cond_output: + pred_masks = inference_session.get_output(obj_idx, frame_idx, "pred_masks", is_conditioning_frame=True) + object_score_logits = inference_session.get_output( + obj_idx, frame_idx, "object_score_logits", is_conditioning_frame=True + ) + is_init_cond_frame = True + else: + # Defaults when there are no new inputs + is_init_cond_frame = False + point_inputs = None + mask_inputs = None + + if has_new_inputs: + is_init_cond_frame = frame_idx not in inference_session.frames_tracked_per_obj[obj_idx] + if is_init_cond_frame: + reverse = False + point_inputs = inference_session.point_inputs_per_obj[obj_idx].get(frame_idx, None) + mask_inputs = inference_session.mask_inputs_per_obj[obj_idx].get(frame_idx, None) + if point_inputs is not None or mask_inputs is not None: + inference_session.obj_with_new_inputs.remove(obj_id) + + current_out = self._run_single_frame_inference( + inference_session=inference_session, + obj_idx=obj_idx, + frame_idx=frame_idx, + batch_size=1, # run on the slice of a single object + is_init_cond_frame=is_init_cond_frame, + point_inputs=point_inputs, + mask_inputs=mask_inputs, + reverse=reverse, + streaming=frame is not None, + ) + inference_session.store_output( + obj_idx, frame_idx, output_value=current_out, is_conditioning_frame=is_init_cond_frame + ) + pred_masks = current_out["pred_masks"] + object_score_logits = current_out["object_score_logits"] + + # Collect data for batched memory encoding + if run_mem_encoder and self.num_maskmem > 0: + objects_needing_memory_encoding.append(obj_idx) + high_res_masks_for_memory.append(current_out["high_res_masks"]) + object_score_logits_for_memory.append(object_score_logits) + is_mask_from_pts_per_obj.append(point_inputs is not None or mask_inputs is not None) + + pred_masks_per_obj[obj_idx] = pred_masks + object_score_logits_per_obj[obj_idx] = object_score_logits.squeeze(-1) + if not is_init_cond_frame: + # only for tracked frames, not for initial conditioning frames + inference_session.frames_tracked_per_obj[obj_idx][frame_idx] = {"reverse": reverse} + + # Batch encode memories for all objects at once + self._batch_encode_memories( + inference_session=inference_session, + frame_idx=frame_idx, + objects_needing_memory_encoding=objects_needing_memory_encoding, + high_res_masks_for_memory=high_res_masks_for_memory, + object_score_logits_for_memory=object_score_logits_for_memory, + is_mask_from_pts_per_obj=is_mask_from_pts_per_obj, + ) + + # Resize the output mask to the original video resolution (we directly use + # the mask scores on GPU for output to avoid any CPU conversion in between) + if len(pred_masks_per_obj) > 1: + all_pred_masks = torch.cat(pred_masks_per_obj, dim=0) + all_object_score_logits = torch.cat(object_score_logits_per_obj, dim=0) + else: + all_pred_masks = pred_masks_per_obj[0] + all_object_score_logits = object_score_logits_per_obj[0] + + return Sam2VideoSegmentationOutput( + object_ids=inference_session.obj_ids.copy(), + pred_masks=all_pred_masks, + object_score_logits=all_object_score_logits, + frame_idx=frame_idx, + ) + + @can_return_tuple + @auto_docstring + def get_image_features( + self, + pixel_values: torch.FloatTensor, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple | Sam2VideoVisionEncoderOutput: + r""" + pixel_values (`torch.FloatTensor`): + Input pixel values of shape `(batch_size, num_channels, height, width)`. + """ + vision_outputs: Sam2VideoVisionEncoderOutput = self.vision_encoder(pixel_values, return_dict=True, **kwargs) + + feature_maps = vision_outputs.fpn_hidden_states + feature_maps_position_embeddings = vision_outputs.fpn_position_encoding + + # precompute projected level 0 and level 1 features in SAM decoder + # to avoid running it again on every SAM click + feature_maps = list(feature_maps) + feature_maps[0] = self.mask_decoder.conv_s0(feature_maps[0]) + feature_maps[1] = self.mask_decoder.conv_s1(feature_maps[1]) + + # flatten NxCxHxW to HWxNxC + feature_maps = [feature_map.flatten(2).permute(2, 0, 1) for feature_map in feature_maps] + feature_maps_position_embeddings = [ + feature_map_position_embedding.flatten(2).permute(2, 0, 1) + for feature_map_position_embedding in feature_maps_position_embeddings + ] + vision_outputs.fpn_hidden_states = feature_maps + vision_outputs.fpn_position_encoding = feature_maps_position_embeddings + + return vision_outputs + + def _prepare_vision_features( + self, + inference_session: Sam2VideoInferenceSession, + frame_idx: int, + batch_size: int, + ) -> tuple[torch.Tensor, list[torch.Tensor]]: + """Prepare vision features for a frame.""" + + # Check if features are cached + if cached_features := inference_session.cache.get_vision_features(frame_idx): + vision_feats = cached_features["vision_feats"] + vision_pos_embeds = cached_features["vision_pos_embeds"] + else: + # Compute features using image encoder + image_batch = inference_session.get_frame(frame_idx).unsqueeze(0) # Add batch dimension + image_outputs = self.get_image_features(image_batch, return_dict=True) + vision_feats = image_outputs.fpn_hidden_states + vision_pos_embeds = image_outputs.fpn_position_encoding + # Cache features + inference_session.cache.cache_vision_features( + frame_idx, {"vision_feats": vision_feats, "vision_pos_embeds": vision_pos_embeds} + ) + + # Expand to batch size if needed + if batch_size > 1: + vision_feats = vision_feats.expand(batch_size, -1, -1, -1) + vision_pos_embeds = [pe.expand(batch_size, -1, -1, -1) for pe in vision_pos_embeds] + + return vision_feats, vision_pos_embeds + + def _single_frame_forward( + self, + pixel_values: torch.FloatTensor | None = None, + input_points: torch.FloatTensor | None = None, + input_labels: torch.LongTensor | None = None, + input_boxes: torch.FloatTensor | None = None, + input_masks: torch.LongTensor | None = None, + image_embeddings: torch.FloatTensor | None = None, + multimask_output: bool = True, + attention_similarity: torch.FloatTensor | None = None, + target_embedding: torch.FloatTensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> Sam2VideoImageSegmentationOutput: + """ + input_points (`torch.FloatTensor` of shape `(batch_size, num_points, 2)`): + Input 2D spatial points, this is used by the prompt encoder to encode the prompt. Generally yields to much + better results. The points can be obtained by passing a list of list of list to the processor that will + create corresponding `torch` tensors of dimension 4. The first dimension is the image batch size, the + second dimension is the point batch size (i.e. how many segmentation masks do we want the model to predict + per input point), the third dimension is the number of points per segmentation mask (it is possible to pass + multiple points for a single mask), and the last dimension is the x (vertical) and y (horizontal) + coordinates of the point. If a different number of points is passed either for each image, or for each + mask, the processor will create "PAD" points that will correspond to the (0, 0) coordinate, and the + computation of the embedding will be skipped for these points using the labels. + input_labels (`torch.LongTensor` of shape `(batch_size, point_batch_size, num_points)`): + Input labels for the points, this is used by the prompt encoder to encode the prompt. According to the + official implementation, there are 3 types of labels + + - `1`: the point is a point that contains the object of interest + - `0`: the point is a point that does not contain the object of interest + - `-1`: the point corresponds to the background + + We added the label: + + - `-10`: the point is a padding point, thus should be ignored by the prompt encoder + + The padding labels should be automatically done by the processor. + input_boxes (`torch.FloatTensor` of shape `(batch_size, num_boxes, 4)`): + Input boxes for the points, this is used by the prompt encoder to encode the prompt. Generally yields to + much better generated masks. The boxes can be obtained by passing a list of list of list to the processor, + that will generate a `torch` tensor, with each dimension corresponding respectively to the image batch + size, the number of boxes per image and the coordinates of the top left and bottom right point of the box. + In the order (`x1`, `y1`, `x2`, `y2`): + + - `x1`: the x coordinate of the top left point of the input box + - `y1`: the y coordinate of the top left point of the input box + - `x2`: the x coordinate of the bottom right point of the input box + - `y2`: the y coordinate of the bottom right point of the input box + input_masks (`torch.FloatTensor` of shape `(batch_size, image_size, image_size)`): + SAM model also accepts segmentation masks as input. The mask will be embedded by the prompt encoder to + generate a corresponding embedding, that will be fed later on to the mask decoder. These masks needs to be + manually fed by the user, and they need to be of shape (`batch_size`, `image_size`, `image_size`). + image_embeddings (`torch.FloatTensor` of shape `(batch_size, output_channels, window_size, window_size)`): + Image embeddings, this is used by the mask decoder to generate masks and iou scores. For more memory + efficient computation, users can first retrieve the image embeddings using the `get_image_embeddings` + method, and then feed them to the `forward` method instead of feeding the `pixel_values`. + multimask_output (`bool`, *optional*): + In the original implementation and paper, the model always outputs 3 masks per image (or per point / per + bounding box if relevant). However, it is possible to just output a single mask, that corresponds to the + "best" mask, by specifying `multimask_output=False`. + attention_similarity (`torch.FloatTensor`, *optional*): + Attention similarity tensor, to be provided to the mask decoder for target-guided attention in case the + model is used for personalization as introduced in [PerSAM](https://huggingface.co/papers/2305.03048). + target_embedding (`torch.FloatTensor`, *optional*): + Embedding of the target concept, to be provided to the mask decoder for target-semantic prompting in case + the model is used for personalization as introduced in [PerSAM](https://huggingface.co/papers/2305.03048). + """ + if not ((pixel_values is None) ^ (image_embeddings is None)): + raise ValueError("Exactly one of pixel_values or image_embeddings must be provided.") + if input_points is not None and input_boxes is not None: + if input_points.shape[1] != input_boxes.shape[1]: + raise ValueError( + f"You should provide as many bounding boxes as input points per box. Got {input_points.shape[1]} and {input_boxes.shape[1]}." + ) + elif input_points is not None: + num_objects = input_points.shape[1] + elif input_boxes is not None: + num_objects = input_boxes.shape[1] + elif input_masks is not None: + num_objects = input_masks.shape[1] + else: + num_objects = 1 + + image_positional_embeddings = self.get_image_wide_positional_embeddings() + # repeat with batch size + batch_size = pixel_values.shape[0] if pixel_values is not None else image_embeddings[-1].shape[0] + image_positional_embeddings = image_positional_embeddings.repeat(batch_size, 1, 1, 1) + + vision_attentions = None + vision_hidden_states = None + + if pixel_values is not None: + image_outputs = self.get_image_features(pixel_values, return_dict=True, **kwargs) + feature_maps = image_outputs.fpn_hidden_states + vision_hidden_states = image_outputs.hidden_states + vision_attentions = image_outputs.attentions + + # add no memory embedding to the last feature map + feature_maps[-1] = feature_maps[-1] + self.no_memory_embedding + + # reshape feature maps to the same shape as the backbone feature sizes + image_embeddings = [ + feat.permute(1, 2, 0).view(batch_size, -1, *feat_size) + for feat, feat_size in zip(feature_maps, self.backbone_feature_sizes) + ] + + if input_points is not None and input_labels is None: + input_labels = torch.ones_like(input_points[:, :, :, 0], dtype=torch.int, device=input_points.device) + + if input_points is None and input_boxes is None: + # If no points are provide, pad with an empty point (with label -1) + input_points = torch.zeros( + batch_size, 1, 1, 2, dtype=image_embeddings[-1].dtype, device=image_embeddings[-1].device + ) + input_labels = -torch.ones(batch_size, 1, 1, dtype=torch.int32, device=image_embeddings[-1].device) + + if input_masks is not None: + # If mask_inputs is provided, downsize it into low-res mask input if needed + # and feed it as a dense mask prompt into the SAM mask encoder + if input_masks.shape[-2:] != self.prompt_encoder.mask_input_size: + input_masks = F.interpolate( + input_masks.float(), + size=self.prompt_encoder.mask_input_size, + align_corners=False, + mode="bilinear", + antialias=True, # use antialias for downsampling + ).to(input_masks.dtype) + + sparse_embeddings, dense_embeddings = self.prompt_encoder( + input_points=input_points, + input_labels=input_labels, + input_boxes=input_boxes, + input_masks=input_masks, + ) + low_res_multimasks, iou_scores, sam_output_tokens, object_score_logits = self.mask_decoder( + image_embeddings=image_embeddings[-1], + image_positional_embeddings=image_positional_embeddings, + sparse_prompt_embeddings=sparse_embeddings, + dense_prompt_embeddings=dense_embeddings, + multimask_output=multimask_output, + high_resolution_features=image_embeddings[:-1], + attention_similarity=attention_similarity, + target_embedding=target_embedding, + **kwargs, + ) + + is_obj_appearing = object_score_logits > 0 + # Mask used for spatial memories is always a *hard* choice between obj and no obj, + # consistent with the actual mask prediction + low_res_multimasks = torch.where( + is_obj_appearing[:, None, None], + low_res_multimasks, + NO_OBJ_SCORE, + ) + + # convert masks from possibly bfloat16 (or float16) to float32 + # (older PyTorch versions before 2.1 don't support `interpolate` on bf16) + high_res_multimasks = ( + F.interpolate( + low_res_multimasks.squeeze(1).float(), + size=(self.image_size, self.image_size), + mode="bilinear", + align_corners=False, + ) + .unsqueeze(1) + .to(low_res_multimasks.dtype) + ) + sam_output_token = sam_output_tokens[:, :, 0] + if multimask_output: + # take the best mask prediction (with the highest IoU estimation) + best_iou_inds = torch.argmax(iou_scores, dim=-1) + batch_inds = torch.arange(batch_size, device=high_res_multimasks.device) + object_batch_inds = torch.arange(num_objects, device=high_res_multimasks.device) + low_res_masks = low_res_multimasks[batch_inds, object_batch_inds, best_iou_inds] + high_res_masks = high_res_multimasks[batch_inds, object_batch_inds, best_iou_inds] + if sam_output_tokens.size(2) > 1: + sam_output_token = sam_output_tokens[batch_inds, object_batch_inds, best_iou_inds] + else: + low_res_masks, high_res_masks = low_res_multimasks[:, :, 0], high_res_multimasks[:, :, 0] + + # Extract object pointer from the SAM output token (with occlusion handling) + object_pointer = self.object_pointer_proj(sam_output_token) + lambda_is_obj_appearing = is_obj_appearing.to(object_pointer.dtype) + + object_pointer = lambda_is_obj_appearing * object_pointer + object_pointer = object_pointer + (1 - lambda_is_obj_appearing) * self.no_object_pointer + + return Sam2VideoImageSegmentationOutput( + iou_scores=iou_scores, + pred_masks=low_res_masks, + high_res_masks=high_res_masks, + object_pointer=object_pointer, + object_score_logits=object_score_logits, + image_embeddings=image_embeddings, + vision_hidden_states=vision_hidden_states, + vision_attentions=vision_attentions, + ) + + def _use_mask_as_output( + self, + backbone_features: torch.Tensor, + high_res_features: list[torch.Tensor], + mask_inputs: torch.Tensor, + ) -> Sam2VideoImageSegmentationOutput: + """ + Directly turn binary `mask_inputs` into a output mask logits without using SAM. + (same input and output shapes as in forward above). + """ + # Use -10/+20 as logits for neg/pos pixels (very close to 0/1 in prob after sigmoid). + out_scale, out_bias = 20.0, -10.0 # sigmoid(-10.0)=4.5398e-05 + mask_inputs_float = mask_inputs.to(backbone_features[0].dtype) + + # Ensure mask is at self.image_size resolution for consistency + if mask_inputs_float.shape[-2:] != (self.image_size, self.image_size): + mask_inputs_float = F.interpolate( + mask_inputs_float.float(), + size=(self.image_size, self.image_size), + align_corners=False, + mode="bilinear", + antialias=True, + ).to(mask_inputs.dtype) + + high_res_masks = mask_inputs_float * out_scale + out_bias + low_res_masks = F.interpolate( + high_res_masks.float(), + size=self.prompt_encoder.mask_input_size, + align_corners=False, + mode="bilinear", + antialias=True, # use antialias for downsampling + ).to(backbone_features[0].dtype) + # a dummy IoU prediction of all 1's under mask input + iou_scores = mask_inputs.new_ones(mask_inputs.size(0), 1).to(backbone_features[0].dtype) + # produce an object pointer using the SAM decoder from the mask input + object_pointer = self._single_frame_forward( + input_masks=self.mask_downsample(mask_inputs_float.to(backbone_features[0].dtype)), + image_embeddings=high_res_features + [backbone_features], + ).object_pointer + # In this method, we are treating mask_input as output, e.g. using it directly to create spatial mem; + # Below, we follow the same design axiom to use mask_input to decide if obj appears or not instead of relying + # on the object_scores from the SAM decoder. + is_obj_appearing = torch.any(mask_inputs.flatten(1).float() > 0.0, dim=1) + is_obj_appearing = is_obj_appearing[..., None] + lambda_is_obj_appearing = is_obj_appearing.to(backbone_features[0].dtype) + object_score_logits = out_scale * lambda_is_obj_appearing + out_bias + object_pointer = lambda_is_obj_appearing * object_pointer + object_pointer = object_pointer + (1 - lambda_is_obj_appearing) * self.no_object_pointer + return Sam2VideoImageSegmentationOutput( + iou_scores=iou_scores, + pred_masks=low_res_masks, + high_res_masks=high_res_masks, + object_pointer=object_pointer, + object_score_logits=object_score_logits.unsqueeze(-1), + image_embeddings=high_res_features + [backbone_features], + ) + + def _select_closest_cond_frames(self, frame_idx, cond_frame_outputs, max_cond_frame_num): + """ + Select up to `max_cond_frame_num` conditioning frames from `cond_frame_outputs` + that are temporally closest to the current frame at `frame_idx`. Here, we take + - a) the closest conditioning frame before `frame_idx` (if any); + - b) the closest conditioning frame after `frame_idx` (if any); + - c) any other temporally closest conditioning frames until reaching a total + of `max_cond_frame_num` conditioning frames. + + Outputs: + - selected_outputs: selected items (keys & values) from `cond_frame_outputs`. + - unselected_outputs: items (keys & values) not selected in `cond_frame_outputs`. + """ + if max_cond_frame_num == -1 or len(cond_frame_outputs) <= max_cond_frame_num: + selected_outputs = cond_frame_outputs + unselected_outputs = {} + else: + selected_outputs = {} + # the closest conditioning frame before `frame_idx` (if any) + idx_before = max((t for t in cond_frame_outputs if t < frame_idx), default=None) + if idx_before is not None: + selected_outputs[idx_before] = cond_frame_outputs[idx_before] + + # the closest conditioning frame after `frame_idx` (if any) + idx_after = min((t for t in cond_frame_outputs if t >= frame_idx), default=None) + if idx_after is not None: + selected_outputs[idx_after] = cond_frame_outputs[idx_after] + + # add other temporally closest conditioning frames until reaching a total + # of `max_cond_frame_num` conditioning frames. + num_remain = max_cond_frame_num - len(selected_outputs) + inds_remain = sorted( + (t for t in cond_frame_outputs if t not in selected_outputs), + key=lambda x: abs(x - frame_idx), + )[:num_remain] + selected_outputs.update((t, cond_frame_outputs[t]) for t in inds_remain) + unselected_outputs = {t: v for t, v in cond_frame_outputs.items() if t not in selected_outputs} + + return selected_outputs, unselected_outputs + + def _gather_memory_frame_outputs( + self, + inference_session: Sam2VideoInferenceSession, + obj_idx: int, + frame_idx: int, + track_in_reverse_time: bool = False, + ) -> list[tuple[int, dict]]: + """ + Get memory frames from conditioning and non-conditioning outputs. + + Returns: + List of (relative_temporal_offset, output_data) tuples. + """ + temporal_positions_and_previous_outputs = [] + + # Add conditioning frame outputs (limited by max_cond_frame_num) + conditioning_outputs = inference_session.output_dict_per_obj[obj_idx]["cond_frame_outputs"] + if not conditioning_outputs: + raise ValueError( + "maskmem_features in conditioning outputs cannot be empty when not is_initial_conditioning_frame" + ) + conditioning_outputs, unselected_conditioning_outputs = self._select_closest_cond_frames( + frame_idx, conditioning_outputs, max_cond_frame_num=self.config.max_cond_frame_num + ) + + # Store (temporal_position, output_data) tuples + temporal_positions_and_previous_outputs = [(0, out) for out in conditioning_outputs.values()] + + # Add non-conditioning memory frames (up to self.num_maskmem - 1) + # These are typically frames tracked by the model without direct user input. + # Frames are selected with a stride, prioritizing the most recent ones. Here we only support stride = 1 for simplicity. + for relative_temporal_offset in range(self.num_maskmem - 1, 0, -1): + # relative_temporal_offset: how many frames before (or after if reversing) the current frame + if not track_in_reverse_time: + previous_frame_idx = frame_idx - relative_temporal_offset + else: + previous_frame_idx = frame_idx + relative_temporal_offset + + # check if the output is already stored without using get_output to avoid unnecessary memory transfers between CPU and GPU + output_data = inference_session.output_dict_per_obj[obj_idx]["non_cond_frame_outputs"].get( + previous_frame_idx, unselected_conditioning_outputs.get(previous_frame_idx, None) + ) + + temporal_positions_and_previous_outputs.append((relative_temporal_offset, output_data)) + + return temporal_positions_and_previous_outputs + + def _build_memory_attention_inputs( + self, + temporal_positions_and_previous_outputs: list[tuple[int, dict]], + device: torch.device, + ) -> tuple[list[torch.Tensor], list[torch.Tensor]]: + """ + Concatenate memory features and positional embeddings from previous frames. + + Returns: + Tuple of (memories_to_concatenate, memory_positional_embeddings_to_concatenate). + """ + memories_to_concatenate = [] + memory_positional_embeddings_to_concatenate = [] + + for relative_temporal_offset, prev_output_data in temporal_positions_and_previous_outputs: + if prev_output_data is None: + continue # Skip if no output data for this temporal position (e.g., padding frames) + + # Load memory features (potentially from CPU to GPU) + # Features are flattened: (Batch, Channels, H, W) -> (H*W, Batch, Channels) + memory_features = prev_output_data["maskmem_features"].to(device, non_blocking=True) + memories_to_concatenate.append(memory_features) + + # Spatial positional encoding (potentially from CPU to GPU) + spatial_memory_pos_embed = prev_output_data["maskmem_pos_enc"].to(device, non_blocking=True) + + # Add temporal positional encoding + # self.memory_temporal_positional_encoding shape: (NumMaskMem, 1, 1, MemDim) + combined_memory_pos_embed = ( + spatial_memory_pos_embed + self.memory_temporal_positional_encoding[relative_temporal_offset - 1] + ) + memory_positional_embeddings_to_concatenate.append(combined_memory_pos_embed) + + return memories_to_concatenate, memory_positional_embeddings_to_concatenate + + def _get_object_pointers( + self, + inference_session: Sam2VideoInferenceSession, + obj_idx: int, + frame_idx: int, + num_total_frames: int, + device: torch.device, + track_in_reverse_time: bool = False, + streaming: bool = False, + ) -> tuple[list[int], list[torch.Tensor], int]: + """ + Get object pointers and their positional embeddings from past frames. + + Returns: + Tuple of (temporal_offsets, pointer_tokens, max_object_pointers_to_use). + """ + temporal_position_sign_multiplier = -1 if track_in_reverse_time else 1 + + # Determine max object pointers to use + if streaming: + max_object_pointers_to_use = self.config.max_object_pointers_in_encoder + else: + max_object_pointers_to_use = min(num_total_frames, self.config.max_object_pointers_in_encoder) + + temporal_offsets: list[int] = [] + pointer_tokens: list[torch.Tensor] = [] + + # Add object pointers from selected conditioning frames + # Optionally, only include pointers from past frames during evaluation + conditioning_outputs = inference_session.output_dict_per_obj[obj_idx]["cond_frame_outputs"] + eligible_conditioning_outputs = conditioning_outputs + if not self.training: + eligible_conditioning_outputs = { + temporal_idx: out + for temporal_idx, out in conditioning_outputs.items() + if (temporal_idx >= frame_idx if track_in_reverse_time else temporal_idx <= frame_idx) + } + + for temporal_idx, out_data in eligible_conditioning_outputs.items(): + temporal_difference = (frame_idx - temporal_idx) * temporal_position_sign_multiplier + temporal_offsets.append(temporal_difference) + pointer_tokens.append(out_data["object_pointer"].to(device)) + + # Add object pointers from non-conditioning frames (up to max_object_pointers_to_use - 1) + for t_diff_offset in range(1, max_object_pointers_to_use): + ref_frame_idx = frame_idx + t_diff_offset if track_in_reverse_time else frame_idx - t_diff_offset + if ref_frame_idx < 0 or ( + not streaming and num_total_frames is not None and ref_frame_idx >= num_total_frames + ): + break # Stop if frame index is out of bounds + + # check if the output is already stored without using get_output to avoid unnecessary memory transfers between CPU and GPU + out_data = inference_session.output_dict_per_obj[obj_idx]["non_cond_frame_outputs"].get( + ref_frame_idx, None + ) + if out_data is not None: + temporal_offsets.append(t_diff_offset) + pointer_tokens.append(out_data["object_pointer"].to(device)) + + return temporal_offsets, pointer_tokens, max_object_pointers_to_use + + def _process_object_pointers( + self, + temporal_offsets: list[int], + pointer_tokens: list[torch.Tensor], + max_object_pointers_to_use: int, + batch_size: int, + num_channels: int, + device: torch.device, + ) -> tuple[torch.Tensor, torch.Tensor]: + """ + Process object pointers and compute their positional embeddings. + + Returns: + Tuple of (object_pointers, object_pointers_pos_embed). + """ + if not pointer_tokens: + return None, None + + # Stack object pointers: List of (Batch, Channels) -> (SeqLen_ptr, Batch, Channels) + object_pointers = torch.stack(pointer_tokens, dim=0) + + if self.config.enable_temporal_pos_encoding_for_object_pointers: + max_temporal_diff = float(max_object_pointers_to_use - 1) + # Determine dimensionality for temporal positional encoding of pointers + pointer_tpos_dim = num_channels + + # Normalize temporal differences before sine PE calculation + normalized_temporal_diffs = ( + torch.tensor(temporal_offsets, device=device, dtype=torch.float32) / max_temporal_diff + ) + sine_pe = get_1d_sine_pe(normalized_temporal_diffs, dim=pointer_tpos_dim).to(object_pointers.dtype) + projected_sine_pe = self.temporal_positional_encoding_projection_layer(sine_pe) + object_pointers_pos_embed = projected_sine_pe.unsqueeze(1).expand(-1, batch_size, self.mem_dim) + else: + object_pointers_pos_embed = object_pointers.new_zeros( + len(temporal_offsets), batch_size, self.mem_dim, dtype=object_pointers.dtype + ) + + if self.mem_dim < num_channels: + # If memory dimension is smaller, reshape/split pointers and repeat positional encoding + num_splits = num_channels // self.mem_dim + object_pointers = object_pointers.reshape(-1, batch_size, num_splits, self.mem_dim) + object_pointers = object_pointers.permute(0, 2, 1, 3).flatten( + 0, 1 + ) # (SeqLen_ptr*num_splits, Batch, MemDim) + object_pointers_pos_embed = object_pointers_pos_embed.repeat_interleave(num_splits, dim=0) + + return object_pointers, object_pointers_pos_embed + + def _prepare_memory_conditioned_features( + self, + inference_session: Sam2VideoInferenceSession, + frame_idx: int, + obj_idx: int, + is_initial_conditioning_frame: bool, + current_vision_features: list[torch.Tensor], + current_vision_positional_embeddings: list[torch.Tensor], + num_total_frames: int, + track_in_reverse_time: bool = False, + streaming: bool = False, + ) -> torch.Tensor: + """ + Fuse current frame's visual features with memory from previous frames for enhanced object tracking. + + This method conditions the current frame's visual features on temporal memory from previous frames, + enabling consistent object tracking across video sequences. For initial conditioning frames, it uses + no-memory embeddings. For subsequent frames, it retrieves and integrates memory features from both + conditioning frames (user interactions) and non-conditioning frames (tracked results) via cross-attention. + + Args: + inference_session (`Sam2VideoInferenceSession`): + The video inference session object. + frame_idx (`int`): + Index of the current frame being processed. + obj_idx (`int`): + Index of the object being processed. + is_initial_conditioning_frame (`bool`): + Whether this is an initial conditioning frame with user inputs (True) or a subsequent + tracking frame (False). + current_vision_features (`torch.Tensor`): + Highest-level vision features of shape `(seq_len, batch_size, channels)`. + current_vision_positional_embeddings (`torch.Tensor`): + Positional embedding tensors corresponding to the highest-level vision features. + num_total_frames (`int`): + Total number of frames in the video sequence. + track_in_reverse_time (`bool`, *optional*, defaults to `False`): + Whether tracking is performed in reverse temporal order. + streaming (`bool`, *optional*, defaults to `False`): + Whether this is streaming inference mode. + + Returns: + `torch.Tensor`: Memory-conditioned feature tensor of shape `(batch_size, channels, height, width)` + suitable for input to the SAM decoder. + """ + # Get dimensions from the highest-level (lowest-resolution) feature map + batch_size = current_vision_features.size(1) + num_channels = self.hidden_dim + height, width = self.backbone_feature_sizes[-1] + device = current_vision_features.device + + # If memory is disabled (e.g., for single image SAM), return current features directly. + if self.num_maskmem == 0: + # Permute (SeqLen, Batch, Channels) -> (Batch, Channels, SeqLen) then view as (Batch, Channels, Height, Width) + # Assuming SeqLen = Height * Width for the last feature map + current_feature_map = current_vision_features.permute(1, 2, 0).view( + batch_size, num_channels, height, width + ) + return current_feature_map + + # Step 1: Handle initial conditioning frames + if is_initial_conditioning_frame: + # For initial conditioning frames, no prior memory is used directly in this block. + # If configured, directly add a learnable "no memory" embedding. + # current_vision_features has shape (SeqLen, Batch, Channels) + conditioned_feature_map_flat = current_vision_features + self.no_memory_embedding + # Reshape to (Batch, Channels, Height, Width) + conditioned_feature_map = conditioned_feature_map_flat.permute(1, 2, 0).view( + batch_size, num_channels, height, width + ) + return conditioned_feature_map + + # Step 2: Get memory frames and concatenate their features + temporal_positions_and_previous_outputs = self._gather_memory_frame_outputs( + inference_session, obj_idx, frame_idx, track_in_reverse_time + ) + + memories_to_concatenate, memory_positional_embeddings_to_concatenate = self._build_memory_attention_inputs( + temporal_positions_and_previous_outputs, device + ) + + # Step 3: Get and process object pointers + temporal_offsets, pointer_tokens, max_object_pointers_to_use = self._get_object_pointers( + inference_session, obj_idx, frame_idx, num_total_frames, device, track_in_reverse_time, streaming + ) + + num_object_pointer_tokens = 0 + if pointer_tokens: + object_pointers, object_pointers_pos_embed = self._process_object_pointers( + temporal_offsets, pointer_tokens, max_object_pointers_to_use, batch_size, num_channels, device + ) + + if object_pointers is not None: + memories_to_concatenate.append(object_pointers) + memory_positional_embeddings_to_concatenate.append(object_pointers_pos_embed) + num_object_pointer_tokens = object_pointers.shape[0] + + # Step 4: Concatenate all retrieved memories and their positional embeddings + combined_memory = torch.cat(memories_to_concatenate, dim=0).to(dtype=inference_session.dtype) + combined_memory_positional_embeddings = torch.cat(memory_positional_embeddings_to_concatenate, dim=0) + + # Step 5: Forward through the memory attention mechanism + conditioned_feature_map_flat = self.memory_attention( + current_vision_features=current_vision_features, + current_vision_position_embeddings=current_vision_positional_embeddings, + memory=combined_memory, + memory_posision_embeddings=combined_memory_positional_embeddings, # Corrected typo from API + num_object_pointer_tokens=num_object_pointer_tokens, + ) + + # Reshape from (Batch, H*W, Channels) to (Batch, Channels, Height, Width) + conditioned_feature_map = ( + conditioned_feature_map_flat.squeeze(1).permute(0, 2, 1).view(batch_size, num_channels, height, width) + ) + return conditioned_feature_map + + def _use_multimask(self, is_init_cond_frame: bool, point_inputs: dict | None) -> bool: + """Whether to use multimask output in the SAM head.""" + num_pts = 0 if point_inputs is None else point_inputs["point_labels"].size(2) + multimask_output = ( + self.config.multimask_output_in_sam + and (is_init_cond_frame or self.config.multimask_output_for_tracking) + and (self.config.multimask_min_pt_num <= num_pts <= self.config.multimask_max_pt_num) + ) + return multimask_output + + def _run_single_frame_inference( + self, + inference_session: Sam2VideoInferenceSession, + frame_idx: int, + obj_idx: int, + batch_size: int, + is_init_cond_frame: bool, + point_inputs: torch.Tensor | None, + mask_inputs: torch.Tensor | None, + reverse: bool, + prev_sam_mask_logits: torch.Tensor | None = None, + streaming: bool = False, + ) -> dict[str, Any]: + """ + Perform a single tracking step for video object segmentation. + + Args: + inference_session (`Sam2VideoInferenceSession`): + The video inference session object. + frame_idx (`int`): + Index of the current frame. + obj_idx (`int`): + Index of the current object. + batch_size (`int`): + Batch size of the current frame. + is_init_cond_frame (`bool`): + Whether this is an initial conditioning frame with user inputs. + point_inputs (`dict`, *optional*): + Point prompt inputs for the current frame. + mask_inputs (`torch.Tensor`, *optional*): + Mask prompt inputs for the current frame. + reverse (`bool`, *optional*, defaults to `False`): + Whether to track in reverse time order. + prev_sam_mask_logits (`torch.Tensor`, *optional*): + Previously predicted SAM mask logits that can be fed with new clicks. + streaming (`bool`, *optional*, defaults to `False`): + Whether this is streaming inference. + + Returns: + `dict`: Dictionary containing the tracking results for the current frame, including: + - pred_masks: Predicted low-resolution masks. + - object_pointer: Object pointer for memory. + - high_res_masks: High-resolution masks for batched memory encoding. + - object_score_logits: Object score logits (inference only). + """ + # Retrieve correct image features + current_vision_feats, current_vision_pos_embeds = self._prepare_vision_features( + inference_session, frame_idx, batch_size + ) + # point and mask should not appear as input simultaneously on the same frame + if point_inputs is not None and mask_inputs is not None: + raise ValueError( + "point_inputs and mask_inputs should not appear as input simultaneously on the same frame" + ) + # High-resolution feature maps for the SAM head, reshape (HW)BC => BCHW + if len(current_vision_feats) > 1: + high_res_features = [ + x.permute(1, 2, 0).view(x.size(1), x.size(2), *s) + for x, s in zip(current_vision_feats[:-1], self.backbone_feature_sizes[:-1]) + ] + else: + high_res_features = None + if mask_inputs is not None: + # We directly output the mask input (see it as a GT mask) without using a SAM prompt encoder + mask decoder. + pix_feat = current_vision_feats[-1].permute(1, 2, 0) + pix_feat = pix_feat.view(-1, self.hidden_dim, *self.backbone_feature_sizes[-1]) + sam_outputs = self._use_mask_as_output(pix_feat, high_res_features, mask_inputs) + else: + # fused the visual feature with previous memory features in the memory bank + pix_feat = self._prepare_memory_conditioned_features( + inference_session=inference_session, + frame_idx=frame_idx, + obj_idx=obj_idx, + is_initial_conditioning_frame=is_init_cond_frame, + current_vision_features=current_vision_feats[-1], + current_vision_positional_embeddings=current_vision_pos_embeds[-1], + num_total_frames=inference_session.num_frames, + track_in_reverse_time=reverse, + streaming=streaming, + ) + # apply SAM-style segmentation head + # here we might feed previously predicted low-res SAM mask logits into the SAM mask decoder, + # e.g. in demo where such logits come from earlier interaction instead of correction sampling + # (in this case, any `mask_inputs` shouldn't reach here as they are sent to _use_mask_as_output instead) + if prev_sam_mask_logits is not None: + mask_inputs = prev_sam_mask_logits + multimask_output = self._use_multimask(is_init_cond_frame, point_inputs) + sam_outputs = self._single_frame_forward( + pixel_values=None, # Vision features already computed + input_points=point_inputs["point_coords"] if point_inputs is not None else None, + input_labels=point_inputs["point_labels"] if point_inputs is not None else None, + input_masks=mask_inputs, + image_embeddings=high_res_features + [pix_feat], + multimask_output=multimask_output, + ) + + # Memory encoding is now handled in batch by the caller (forward method) + current_out = { + "pred_masks": sam_outputs.pred_masks, + "object_pointer": sam_outputs.object_pointer, + "high_res_masks": sam_outputs.high_res_masks, # Needed for batched memory encoding + } + if not self.training: + current_out["object_score_logits"] = sam_outputs.object_score_logits + + return current_out + + def _encode_new_memory( + self, + current_vision_feats: torch.Tensor, + pred_masks_high_res: torch.Tensor, + object_score_logits: torch.Tensor, + is_mask_from_pts: bool, + ) -> tuple[torch.Tensor, list[torch.Tensor]]: + """Encode the current image and its prediction into a memory feature.""" + batch_size = current_vision_feats.size(1) # batch size on this frame + channels = self.hidden_dim + height, width = self.backbone_feature_sizes[-1] # top-level (lowest-resolution) feature size + + mask_input_size_h, mask_input_size_w = self.prompt_encoder.mask_input_size + mask_mem_size_h = mask_input_size_h * 4 + mask_mem_size_w = mask_input_size_w * 4 + if pred_masks_high_res.shape[2:] != (mask_mem_size_h, mask_mem_size_w): + # downsample the predicted high-res masks into the mask encoder input size + pred_masks_high_res = F.interpolate( + pred_masks_high_res.float(), + size=(mask_mem_size_h, mask_mem_size_w), + align_corners=False, + mode="bilinear", + antialias=True, # use antialias for downsampling + ).to(pred_masks_high_res.dtype) + + # top-level feature, (HW)BC => BCHW + pix_feat = current_vision_feats.permute(1, 2, 0).view(batch_size, channels, height, width) + if is_mask_from_pts and not self.training: + # binarize the mask logits + mask_for_mem = (pred_masks_high_res > 0).to(pred_masks_high_res.dtype) + else: + # apply sigmoid on the raw mask logits to turn them into range (0, 1) + mask_for_mem = torch.sigmoid(pred_masks_high_res) + # apply scale and bias terms to the sigmoid probabilities + mask_for_mem = mask_for_mem * self.config.sigmoid_scale_for_mem_enc + mask_for_mem = mask_for_mem + self.config.sigmoid_bias_for_mem_enc + + maskmem_features, maskmem_pos_enc = self.memory_encoder( + pix_feat, + mask_for_mem, + ) + # add a no-object embedding to the spatial memory to indicate that the frame + # is predicted to be occluded (i.e. no object is appearing in the frame) + if self.occlusion_spatial_embedding_parameter is not None: + is_obj_appearing = (object_score_logits > 0).float() + maskmem_features += (1 - is_obj_appearing[..., None]) * self.occlusion_spatial_embedding_parameter[ + ..., None, None + ].expand(*maskmem_features.shape) + + # convert to bfloat16 to save memory, and for consistency with the original implementation + maskmem_features = maskmem_features.to(torch.bfloat16).flatten(2).permute(2, 0, 1) + maskmem_pos_enc = maskmem_pos_enc.to(pred_masks_high_res.dtype).flatten(2).permute(2, 0, 1) + + return maskmem_features, maskmem_pos_enc + + def _batch_encode_memories( + self, + inference_session: Sam2VideoInferenceSession, + frame_idx: int, + objects_needing_memory_encoding: list[int], + high_res_masks_for_memory: list[torch.Tensor], + object_score_logits_for_memory: list[torch.Tensor], + is_mask_from_pts_per_obj: list[bool], + ): + """ + Batch encode memories for multiple objects at once. + + Args: + inference_session: The video inference session object + frame_idx: Index of the current frame + objects_needing_memory_encoding: List of object indices that need memory encoding + high_res_masks_for_memory: List of high-resolution masks for each object + object_score_logits_for_memory: List of object score logits for each object + is_mask_from_pts_per_obj: List of booleans indicating if mask is from points for each object + """ + if not objects_needing_memory_encoding: + return + + # Get vision features once for all objects + current_vision_feats, _ = self._prepare_vision_features(inference_session, frame_idx, batch_size=1) + + # Stack all high-res masks and object scores + high_res_masks_batched = torch.cat(high_res_masks_for_memory, dim=0) + object_score_logits_batched = torch.cat(object_score_logits_for_memory, dim=0) + + # Expand vision features to match batch size + expanded_vision_feats = current_vision_feats[-1].expand(-1, len(objects_needing_memory_encoding), -1) + + # Encode all memories in one batch call + maskmem_features_batched, maskmem_pos_enc_batched = self._encode_new_memory( + current_vision_feats=expanded_vision_feats, + pred_masks_high_res=high_res_masks_batched, + object_score_logits=object_score_logits_batched, + is_mask_from_pts=any(is_mask_from_pts_per_obj), + ) + + # Split and store encoded memories per object + for i, obj_idx in enumerate(objects_needing_memory_encoding): + # Extract per-object memory from batched result + maskmem_features = maskmem_features_batched[:, i : i + 1] + maskmem_pos_enc = maskmem_pos_enc_batched[:, i : i + 1] + + # Update the stored output with memory features + output_dict = inference_session.output_dict_per_obj[obj_idx] + # Determine if this was a conditioning frame + storage_key = ( + "cond_frame_outputs" if frame_idx in output_dict["cond_frame_outputs"] else "non_cond_frame_outputs" + ) + if frame_idx in output_dict[storage_key]: + output_dict[storage_key][frame_idx]["maskmem_features"] = maskmem_features + output_dict[storage_key][frame_idx]["maskmem_pos_enc"] = maskmem_pos_enc + + @torch.inference_mode() + @auto_docstring( + custom_intro=""" + Propagate the objects through the video frames. Used when initializing an inference session with a whole video. + Yields Sam2VideoSegmentationOutput for each frame. + """ + ) + def propagate_in_video_iterator( + self, + inference_session: Sam2VideoInferenceSession, + start_frame_idx: int | None = None, + max_frame_num_to_track: int | None = None, + reverse: bool = False, + show_progress_bar: bool = False, + ) -> Iterator[Sam2VideoSegmentationOutput]: + r""" + inference_session (`Sam2VideoInferenceSession`): + The video inference session object. + start_frame_idx (`int`, *optional*): + The starting frame index for propagation. + Need to be provided if `forward` hasn't been called on new inputs yet. + If not provided, the starting frame index will be the earliest frame with input points. + max_frame_num_to_track (`int`, *optional*): + The maximum number of frames to track. + reverse (`bool`, *optional*, defaults to `False`): + Whether to propagate in reverse. + show_progress_bar (`bool`, *optional*, defaults to `False`): + Whether to show a progress bar during propagation. + """ + num_frames = inference_session.num_frames + + # set start index, end index, and processing order + if start_frame_idx is None: + # default: start from the earliest frame with input points + frames_with_inputs = [ + frame_idx + for obj_output_dict in inference_session.output_dict_per_obj.values() + for frame_idx in obj_output_dict["cond_frame_outputs"] + ] + if not frames_with_inputs: + raise ValueError( + "Cannot determine the starting frame index; please specify it manually, or run inference on a frame with inputs first." + ) + start_frame_idx = min(frames_with_inputs) + if max_frame_num_to_track is None: + # default: track all the frames in the video + max_frame_num_to_track = num_frames + if reverse: + end_frame_idx = max(start_frame_idx - max_frame_num_to_track, 0) + if start_frame_idx > 0: + processing_order = range(start_frame_idx, end_frame_idx - 1, -1) + else: + processing_order = [] # skip reverse tracking if starting from frame 0 + else: + end_frame_idx = min(start_frame_idx + max_frame_num_to_track, num_frames - 1) + processing_order = range(start_frame_idx, end_frame_idx + 1) + + for frame_idx in tqdm(processing_order, desc="propagate in video", disable=not show_progress_bar): + sam2_video_output = self(inference_session, frame_idx=frame_idx, reverse=reverse) + yield sam2_video_output + + +__all__ = ["Sam2VideoModel", "Sam2VideoInferenceSession", "Sam2VideoPreTrainedModel"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam2_video/modular_sam2_video.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam2_video/modular_sam2_video.py new file mode 100644 index 0000000000000000000000000000000000000000..d66e0f949171eb2eb8e078a902791ae0f7d4acfe --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam2_video/modular_sam2_video.py @@ -0,0 +1,2580 @@ +# Copyright 2025 The Meta AI Authors and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""PyTorch SAM 2 model.""" + +import math +from collections import OrderedDict +from collections.abc import Callable, Iterator +from dataclasses import dataclass +from typing import Any, Union + +import numpy as np +import torch +import torch.nn as nn +import torch.nn.functional as F +from torch import Tensor +from tqdm import tqdm + +from ... import initialization as init +from ...activations import ACT2FN +from ...configuration_utils import PreTrainedConfig +from ...modeling_flash_attention_utils import FlashAttentionKwargs +from ...modeling_layers import GradientCheckpointingLayer +from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel +from ...processing_utils import ProcessorMixin, Unpack +from ...utils import ( + ModelOutput, + auto_docstring, + logging, +) +from ...utils.generic import TransformersKwargs +from ...utils.output_capturing import OutputRecorder +from ...video_utils import VideoInput +from ..auto import CONFIG_MAPPING, AutoConfig +from ..sam2.configuration_sam2 import ( + Sam2MaskDecoderConfig, + Sam2PromptEncoderConfig, +) +from ..sam2.modeling_sam2 import ( + Sam2FeedForward, + Sam2ImageSegmentationOutput, + Sam2LayerNorm, + Sam2Model, + Sam2PositionalEmbedding, + Sam2SinePositionEmbedding, + Sam2TwoWayAttentionBlock, + eager_attention_forward, +) +from ..sam2.processing_sam2 import Sam2Processor + + +logger = logging.get_logger(__name__) + + +class Sam2VideoPromptEncoderConfig(Sam2PromptEncoderConfig): + pass + + +class Sam2VideoMaskDecoderConfig(Sam2MaskDecoderConfig): + pass + + +class Sam2VideoConfig(PreTrainedConfig): + r""" + [`Sam2Config`] is the configuration class to store the configuration of a [`Sam2Model`]. It is used to instantiate a + SAM2 model according to the specified arguments, defining the memory attention, memory encoder, and image encoder + configs. Instantiating a configuration defaults will yield a similar configuration to that of the SAM 2.1 Hiera-tiny + [facebook/sam2.1-hiera-tiny](https://huggingface.co/facebook/sam2.1-hiera-tiny) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + vision_config (Union[`dict`, `Sam2VisionConfig`], *optional*): + Dictionary of configuration options used to initialize [`Sam2VisionConfig`]. + prompt_encoder_config (Union[`dict`, `Sam2PromptEncoderConfig`], *optional*): + Dictionary of configuration options used to initialize [`Sam2PromptEncoderConfig`]. + mask_decoder_config (Union[`dict`, `Sam2MaskDecoderConfig`], *optional*): + Dictionary of configuration options used to initialize [`Sam2MaskDecoderConfig`]. + initializer_range (`float`, *optional*, defaults to 0.02): + Standard deviation for parameter initialization. + num_maskmem (`int`, *optional*, defaults to 7): + The number of memory slots for the mask memory. + image_size (`int`, *optional*, defaults to 1024): + The size of the input images. + sigmoid_scale_for_mem_enc (`float`, *optional*, defaults to 20.0): + Scale factor for the sigmoid function in the memory encoder. + sigmoid_bias_for_mem_enc (`float`, *optional*, defaults to -10.0): + Bias for the sigmoid function in the memory encoder. + enable_occlusion_spatial_embedding (`bool`, *optional*, defaults to `True`): + Whether to enable spatial embedding for occlusions. + multimask_output_in_sam (`bool`, *optional*, defaults to `True`): + Whether to output multiple masks from the SAM head. + multimask_min_pt_num (`int`, *optional*, defaults to 0): + The minimum number of points to trigger multimask output. + multimask_max_pt_num (`int`, *optional*, defaults to 1): + The maximum number of points to trigger multimask output. + multimask_output_for_tracking (`bool`, *optional*, defaults to `True`): + Whether to use multimask output for tracking. + max_object_pointers_in_encoder (`int`, *optional*, defaults to 16): + The maximum number of object pointers in the encoder. + max_cond_frame_num (`int`, *optional*, defaults to -1): + Maximum number of conditioning frames to use in memory attention. Set to -1 to use all conditioning frames. + enable_temporal_pos_encoding_for_object_pointers (`bool`, *optional*, defaults to `True`): + Whether to enable temporal positional encoding for object pointers. + memory_attention_hidden_size (`int`, *optional*, defaults to 256): + Dimensionality of the memory attention hidden states. + memory_attention_num_layers (`int`, *optional*, defaults to 4): + The number of layers in the memory attention module. + memory_attention_num_attention_heads (`int`, *optional*, defaults to 1): + Number of attention heads for each attention layer in the memory attention. + memory_attention_downsample_rate (`int`, *optional*, defaults to 1): + The downsample rate for the attention layers. + memory_attention_feed_forward_hidden_size (`int`, *optional*, defaults to 2048): + The dimension of the feedforward network in the memory attention module. + memory_attention_feed_forward_hidden_act (`str`, *optional*, defaults to `"relu"`): + The non-linear activation function in the feedforward network in the memory attention module. + memory_attention_dropout (`float`, *optional*, defaults to 0.1): + The dropout rate for the memory attention module. + memory_attention_rope_theta (`float`, *optional*, defaults to 10000): + The Rope theta parameter. + memory_attention_rope_feat_sizes (`list[int]`, *optional*, defaults to `[64, 64]`): + The feature sizes for the Rope positional encoding. + memory_attention_rope_dropout (`float`, *optional*, defaults to 0.1): + The dropout rate for the Rope positional encoding. + memory_encoder_hidden_size (`int`, *optional*, defaults to 256): + Dimensionality of the memory encoder hidden states. + memory_encoder_output_channels (`int`, *optional*, defaults to 64): + The number of output channels for the memory encoder. + mask_downsampler_embed_dim (`int`, *optional*, defaults to 256): + The dimension of the mask downsampler embedding. + mask_downsampler_kernel_size (`int`, *optional*, defaults to 3): + The kernel size for the mask downsampler. + mask_downsampler_stride (`int`, *optional*, defaults to 2): + The stride for the mask downsampler. + mask_downsampler_padding (`int`, *optional*, defaults to 1): + The padding for the mask downsampler. + mask_downsampler_total_stride (`int`, *optional*, defaults to 16): + The total stride for the mask downsampler. + mask_downsampler_hidden_act (`str`, *optional*, defaults to `"gelu"`): + The non-linear activation function in the mask downsampler. + memory_fuser_num_layers (`int`, *optional*, defaults to 2): + The number of layers in the memory fuser. + memory_fuser_embed_dim (`int`, *optional*, defaults to 256): + The dimension of the embedding layer in the memory fuser. + memory_fuser_intermediate_dim (`int`, *optional*, defaults to 1024): + The dimension of the intermediate layer in the memory fuser. + memory_fuser_kernel_size (`int`, *optional*, defaults to 7): + The kernel size for the memory fuser. + memory_fuser_padding (`int`, *optional*, defaults to 3): + The padding for the memory fuser. + memory_fuser_layer_scale_init_value (`float`, *optional*, defaults to 1e-06): + The initial value for the layer scale in the memory fuser. + memory_fuser_hidden_act (`str`, *optional*, defaults to `"gelu"`): + The non-linear activation function in the memory fuser. + kwargs (*optional*): + Dictionary of keyword arguments. + + Example: + + ```python + >>> from transformers import ( + ... Sam2VisionConfig, + ... Sam2PromptEncoderConfig, + ... Sam2MaskDecoderConfig, + ... Sam2Model, + ... ) + + >>> # Initializing a Sam2Config with `"facebook/sam2.1_hiera_tiny"` style configuration + >>> configuration = Sam2config() + + >>> # Initializing a Sam2Model (with random weights) from the `"facebook/sam2.1_hiera_tiny"` style configuration + >>> model = Sam2Model(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + + >>> # We can also initialize a Sam2Config from a Sam2VisionConfig, Sam2PromptEncoderConfig, and Sam2MaskDecoderConfig + + >>> # Initializing SAM2 vision encoder, memory attention, and memory encoder configurations + >>> vision_config = Sam2VisionConfig() + >>> prompt_encoder_config = Sam2PromptEncoderConfig() + >>> mask_decoder_config = Sam2MaskDecoderConfig() + + >>> config = Sam2Config(vision_config, prompt_encoder_config, mask_decoder_config) + ```""" + + model_type = "sam2_video" + sub_configs = { + "vision_config": AutoConfig, + "prompt_encoder_config": Sam2VideoPromptEncoderConfig, + "mask_decoder_config": Sam2VideoMaskDecoderConfig, + } + + def __init__( + self, + vision_config=None, + prompt_encoder_config=None, + mask_decoder_config=None, + initializer_range=0.02, + num_maskmem=7, + image_size=1024, + sigmoid_scale_for_mem_enc=20.0, + sigmoid_bias_for_mem_enc=-10.0, + enable_occlusion_spatial_embedding=True, + multimask_output_in_sam=True, + multimask_min_pt_num=0, + multimask_max_pt_num=1, + multimask_output_for_tracking=True, + max_object_pointers_in_encoder=16, + max_cond_frame_num=-1, + enable_temporal_pos_encoding_for_object_pointers=True, + # memory attention + memory_attention_hidden_size=256, + memory_attention_num_layers=4, + memory_attention_num_attention_heads=1, + memory_attention_downsample_rate=1, + memory_attention_feed_forward_hidden_size=2048, + memory_attention_feed_forward_hidden_act="relu", + memory_attention_dropout=0.1, + memory_attention_rope_theta=10000, + memory_attention_rope_feat_sizes=None, + memory_attention_rope_dropout=0.1, + # memory encoder + memory_encoder_hidden_size=256, + memory_encoder_output_channels=64, + mask_downsampler_embed_dim=256, + mask_downsampler_kernel_size=3, + mask_downsampler_stride=2, + mask_downsampler_padding=1, + mask_downsampler_total_stride=16, + mask_downsampler_hidden_act="gelu", + memory_fuser_num_layers=2, + memory_fuser_embed_dim=256, + memory_fuser_intermediate_dim=1024, + memory_fuser_kernel_size=7, + memory_fuser_padding=3, + memory_fuser_layer_scale_init_value=1e-6, + memory_fuser_hidden_act="gelu", + **kwargs, + ): + super().__init__(**kwargs) + + vision_config = vision_config if vision_config is not None else {} + prompt_encoder_config = prompt_encoder_config if prompt_encoder_config is not None else {} + mask_decoder_config = mask_decoder_config if mask_decoder_config is not None else {} + memory_attention_rope_feat_sizes = ( + [64, 64] if memory_attention_rope_feat_sizes is None else memory_attention_rope_feat_sizes + ) + + if isinstance(vision_config, dict): + vision_config["model_type"] = vision_config.get("model_type", "sam2_vision_model") + vision_config = CONFIG_MAPPING[vision_config["model_type"]](**vision_config) + if isinstance(prompt_encoder_config, Sam2VideoPromptEncoderConfig): + prompt_encoder_config = prompt_encoder_config.to_dict() + if isinstance(mask_decoder_config, Sam2VideoMaskDecoderConfig): + mask_decoder_config = mask_decoder_config.to_dict() + + self.vision_config = vision_config + self.prompt_encoder_config = Sam2VideoPromptEncoderConfig(**prompt_encoder_config) + self.mask_decoder_config = Sam2VideoMaskDecoderConfig(**mask_decoder_config) + + self.initializer_range = initializer_range + self.num_maskmem = num_maskmem # default 1 input frame + 6 previous frames + self.image_size = image_size + self.sigmoid_scale_for_mem_enc = sigmoid_scale_for_mem_enc + self.sigmoid_bias_for_mem_enc = sigmoid_bias_for_mem_enc + self.multimask_output_in_sam = multimask_output_in_sam + self.multimask_min_pt_num = multimask_min_pt_num + self.multimask_max_pt_num = multimask_max_pt_num + self.multimask_output_for_tracking = multimask_output_for_tracking + self.max_object_pointers_in_encoder = max_object_pointers_in_encoder + self.max_cond_frame_num = max_cond_frame_num + # The next 4 are True for sam2.1 and False for sam2 + self.enable_occlusion_spatial_embedding = enable_occlusion_spatial_embedding + self.enable_temporal_pos_encoding_for_object_pointers = enable_temporal_pos_encoding_for_object_pointers + + # memory attention + self.memory_attention_hidden_size = memory_attention_hidden_size + self.memory_attention_num_layers = memory_attention_num_layers + self.memory_attention_num_attention_heads = memory_attention_num_attention_heads + self.memory_attention_downsample_rate = memory_attention_downsample_rate + self.memory_attention_feed_forward_hidden_size = memory_attention_feed_forward_hidden_size + self.memory_attention_feed_forward_hidden_act = memory_attention_feed_forward_hidden_act + self.memory_attention_dropout = memory_attention_dropout + self.memory_attention_rope_theta = memory_attention_rope_theta + self.memory_attention_rope_feat_sizes = memory_attention_rope_feat_sizes + self.memory_attention_rope_dropout = memory_attention_rope_dropout + + # memory encoder + self.memory_encoder_hidden_size = memory_encoder_hidden_size + self.memory_encoder_output_channels = memory_encoder_output_channels + self.mask_downsampler_embed_dim = mask_downsampler_embed_dim + self.mask_downsampler_kernel_size = mask_downsampler_kernel_size + self.mask_downsampler_stride = mask_downsampler_stride + self.mask_downsampler_padding = mask_downsampler_padding + self.mask_downsampler_total_stride = mask_downsampler_total_stride + self.mask_downsampler_hidden_act = mask_downsampler_hidden_act + self.memory_fuser_num_layers = memory_fuser_num_layers + self.memory_fuser_embed_dim = memory_fuser_embed_dim + self.memory_fuser_intermediate_dim = memory_fuser_intermediate_dim + self.memory_fuser_kernel_size = memory_fuser_kernel_size + self.memory_fuser_padding = memory_fuser_padding + self.memory_fuser_layer_scale_init_value = memory_fuser_layer_scale_init_value + self.memory_fuser_hidden_act = memory_fuser_hidden_act + + +class Sam2VideoInferenceCache: + """Cache for vision features and model constants.""" + + def __init__( + self, + inference_device: torch.device | str = "cpu", + inference_state_device: torch.device | str = "cpu", + max_vision_features_cache_size: int = 1, + ): + self.inference_device = inference_device + self.inference_state_device = inference_state_device + self.max_vision_features_cache_size = max_vision_features_cache_size + + self._vision_features = {} + + def cache_vision_features(self, frame_idx: int, features: dict): + """Cache vision features with automatic device management.""" + cached = {} + if len(self._vision_features) >= self.max_vision_features_cache_size: + # remove the oldest frame + self._vision_features.pop(min(self._vision_features.keys())) + + for key, value in features.items(): + if isinstance(value, torch.Tensor): + cached[key] = value.to(self.inference_state_device, non_blocking=True) + elif isinstance(value, (list, tuple)) and value and isinstance(value[0], torch.Tensor): + cached[key] = [v.to(self.inference_state_device, non_blocking=True) for v in value] + else: + cached[key] = value + self._vision_features[frame_idx] = cached + + def get_vision_features(self, frame_idx: int) -> dict | None: + """Get cached vision features, automatically moved to inference device.""" + if frame_idx not in self._vision_features: + return None + + cached = self._vision_features[frame_idx] + moved = {} + for key, value in cached.items(): + if isinstance(value, torch.Tensor): + moved[key] = value.to(self.inference_device, non_blocking=True) + elif isinstance(value, (list, tuple)) and value and isinstance(value[0], torch.Tensor): + moved[key] = [v.to(self.inference_device, non_blocking=True) for v in value] + else: + moved[key] = value + return moved + + def clear_all(self): + """Clear all cached data.""" + self._vision_features.clear() + + +class Sam2VideoInferenceSession: + r""" + Manages video inference session parameters, state and cache. + + Args: + video (`torch.FloatTensor`, *optional*): + The video to process. No need to provide when streaming. + video_height (`int`, *optional*): + The height of the video. + video_width (`int`, *optional*): + The width of the video. + inference_device (`torch.device`, *optional*, defaults to `"cpu"`): + The device to use for inference. + inference_state_device (`torch.device`, *optional*, defaults to `"cpu"`): + The device to store the inference state on. + video_storage_device (`torch.device`, *optional*, defaults to `"cpu"`): + The device to store the video on. + dtype (`torch.dtype`, *optional*, defaults to `"float32"`): + The dtype to use for the video. + max_vision_features_cache_size (`int`, *optional*, defaults to 1): + The maximum number of vision features to cache. + """ + + def __init__( + self, + video: torch.FloatTensor | None = None, + video_height: int | None = None, + video_width: int | None = None, + inference_device: torch.device | str = "cpu", + inference_state_device: torch.device | str = "cpu", + video_storage_device: torch.device | str = "cpu", + dtype: torch.dtype | str = "float32", + max_vision_features_cache_size: int = 1, + ): + # store as a dictionary to avoid double memory allocation with torch.cat when adding new frames + self.processed_frames = ( + dict(enumerate(video.to(video_storage_device, dtype=dtype))) if video is not None else None + ) + self.video_height = video_height + self.video_width = video_width + + self.inference_device = inference_device + self.inference_state_device = inference_state_device + self.video_storage_device = video_storage_device + self.dtype = dtype + self.max_vision_features_cache_size = max_vision_features_cache_size + + # Cache for computed features + self.cache = Sam2VideoInferenceCache( + inference_device=self.inference_device, + inference_state_device=self.inference_state_device, + max_vision_features_cache_size=self.max_vision_features_cache_size, + ) + + # Persistent object tracking state + self._obj_id_to_idx = OrderedDict() + self._obj_idx_to_id = OrderedDict() + self.obj_ids = [] + + # Persistent user inputs + self.point_inputs_per_obj = {} + self.mask_inputs_per_obj = {} + + # Persistent model outputs/history + self.output_dict_per_obj = {} + self.frames_tracked_per_obj = {} + + # Session state flags + self.obj_with_new_inputs = [] + + @property + def num_frames(self) -> int | None: + return len(self.processed_frames) if self.processed_frames is not None else None + + # Object management + def obj_id_to_idx(self, obj_id: int) -> int: + """Map object ID to index, creating new entry if needed.""" + obj_idx = self._obj_id_to_idx.get(obj_id, None) + if obj_idx is not None: + return obj_idx + + obj_idx = len(self._obj_id_to_idx) + self._obj_id_to_idx[obj_id] = obj_idx + self._obj_idx_to_id[obj_idx] = obj_id + self.obj_ids = list(self._obj_id_to_idx) + + self.point_inputs_per_obj[obj_idx] = {} + self.mask_inputs_per_obj[obj_idx] = {} + self.output_dict_per_obj[obj_idx] = { + "cond_frame_outputs": {}, + "non_cond_frame_outputs": {}, + } + self.frames_tracked_per_obj[obj_idx] = {} + + return obj_idx + + # Video Inference specific functions + def obj_idx_to_id(self, obj_idx: int) -> int: + """Map model-side object index to client-side object id.""" + return self._obj_idx_to_id[obj_idx] + + def get_obj_num(self) -> int: + """Get the total number of unique object ids received so far in this session.""" + return len(self._obj_idx_to_id) + + # Input management with device handling + def add_point_inputs(self, obj_idx: int, frame_idx: int, inputs: dict): + """Add point inputs with automatic device placement.""" + device_inputs = {} + for key, value in inputs.items(): + if isinstance(value, torch.Tensor): + device_inputs[key] = value.to(self.inference_device, non_blocking=False) + else: + device_inputs[key] = value + self.point_inputs_per_obj[obj_idx][frame_idx] = device_inputs + + def remove_point_inputs(self, obj_idx: int, frame_idx: int): + """Remove point inputs.""" + self.point_inputs_per_obj[obj_idx].pop(frame_idx, None) + + def add_mask_inputs(self, obj_idx: int, frame_idx: int, inputs: torch.Tensor): + """Add mask inputs with automatic device placement.""" + self.mask_inputs_per_obj[obj_idx][frame_idx] = inputs.to( + self.inference_device, dtype=self.dtype, non_blocking=True + ) + + def remove_mask_inputs(self, obj_idx: int, frame_idx: int): + """Remove mask inputs.""" + self.mask_inputs_per_obj[obj_idx].pop(frame_idx, None) + + # Output management with smart device placement + def store_output( + self, + obj_idx: int, + frame_idx: int, + output_key: str | None = None, + output_value: torch.Tensor | dict | None = None, + is_conditioning_frame: bool = True, + ): + """ + Store output with smart device management. + If output_key is None, the output is stored as a dictionary. + + Args: + obj_idx (int): The index of the object. + frame_idx (int): The index of the frame. + output_key (Optional[str]): The key of the output. If None, the output is stored as a dictionary. + output_value (Optional[Union[torch.Tensor, dict]]): The value of the output. + is_conditioning_frame (bool): Whether the output is for a conditioning frame. + """ + storage_key = "cond_frame_outputs" if is_conditioning_frame else "non_cond_frame_outputs" + + if output_key is None and isinstance(output_value, dict): + self.output_dict_per_obj[obj_idx][storage_key][frame_idx] = {} + for key, value in output_value.items(): + self.store_output(obj_idx, frame_idx, key, value, is_conditioning_frame) + return + + # Device placement: small tensors stay on inference device, large ones go to inference state device + if output_key in ["object_pointer", "object_score_logits"]: # Small tensors + self.output_dict_per_obj[obj_idx][storage_key][frame_idx][output_key] = output_value + elif isinstance(output_value, torch.Tensor): # Large tensors like masks, features + self.output_dict_per_obj[obj_idx][storage_key][frame_idx][output_key] = output_value.to( + self.inference_state_device, non_blocking=True + ) + else: + self.output_dict_per_obj[obj_idx][storage_key][frame_idx][output_key] = output_value + + def get_output( + self, + obj_idx: int, + frame_idx: int, + output_key: str, + is_conditioning_frame: bool = True, + ): + """ + Get output with smart device management. + + Args: + obj_idx (int): The index of the object. + frame_idx (int): The index of the frame. + output_key (str): The key of the output. + is_conditioning_frame (bool): Whether the output is for a conditioning frame. + """ + storage_key = "cond_frame_outputs" if is_conditioning_frame else "non_cond_frame_outputs" + out = self.output_dict_per_obj[obj_idx][storage_key].get(frame_idx, None) + # move to inference device if needed + if out is None: + return None + value = out[output_key] + if isinstance(value, torch.Tensor): + value = value.to(self.inference_device, non_blocking=True) + return value + + # Video frame management + def add_new_frame(self, pixel_values: torch.Tensor, frame_idx: int | None = None) -> int: + """Add new frame with automatic device placement.""" + pixel_values = pixel_values.to(self.video_storage_device, dtype=self.dtype, non_blocking=True) + if pixel_values.dim() == 4: + pixel_values = pixel_values.squeeze(0) + + if frame_idx is None: + frame_idx = len(self.processed_frames) if self.processed_frames is not None else 0 + + if self.processed_frames is None: + self.processed_frames = {frame_idx: pixel_values} + else: + self.processed_frames[frame_idx] = pixel_values + + return frame_idx + + def get_frame(self, frame_idx: int) -> torch.Tensor: + """Get frame from video.""" + return self.processed_frames[frame_idx].to(self.inference_device, non_blocking=True) + + def reset_tracking_data(self): + """Reset tracking data but keep cache.""" + self._obj_id_to_idx.clear() + self._obj_idx_to_id.clear() + self.obj_ids.clear() + self.point_inputs_per_obj.clear() + self.mask_inputs_per_obj.clear() + self.output_dict_per_obj.clear() + self.frames_tracked_per_obj.clear() + self.obj_with_new_inputs = [] + # Note: cache and video data are preserved + + def reset_inference_session(self): + """Reset tracking data and cache.""" + self._obj_id_to_idx.clear() + self._obj_idx_to_id.clear() + self.obj_ids.clear() + self.point_inputs_per_obj.clear() + self.mask_inputs_per_obj.clear() + self.output_dict_per_obj.clear() + self.frames_tracked_per_obj.clear() + self.obj_with_new_inputs = [] + self.cache.clear_all() + + +class Sam2VideoProcessor(Sam2Processor): + def __init__( + self, image_processor, video_processor, target_size: int | None = None, point_pad_value: int = -10, **kwargs + ): + ProcessorMixin.__init__(self, image_processor, video_processor, **kwargs) + self.point_pad_value = point_pad_value + self.target_size = target_size if target_size is not None else self.image_processor.size["height"] + + def init_video_session( + self, + video: VideoInput | None = None, + inference_device: Union[str, "torch.device"] = "cpu", + inference_state_device: Union[str, "torch.device"] | None = None, + processing_device: Union[str, "torch.device"] | None = None, + video_storage_device: Union[str, "torch.device"] | None = None, + max_vision_features_cache_size: int = 1, + dtype: torch.dtype = torch.float32, + ): + """ + Initializes a video session for inference. + If a video is provided (async inference), the video will be processed and stored on the `video_storage_device`. + + Args: + video (`VideoInput`, *optional*): + The video to process. No need to provide when streaming. + inference_device (`str` or `torch.device`, *optional*, defaults to "cpu"): + The device to use for inference. + inference_state_device (`str` or `torch.device`, *optional*): + The device to store the inference state on. + processing_device (`str` or `torch.device`, *optional*): + The device to use for video processing. + video_storage_device (`str` or `torch.device`, *optional*): + The device to store the processed video frames on. + max_vision_features_cache_size (`int`, *optional*, defaults to 1): + The maximum number of vision features to cache. + dtype (`torch.dtype`, *optional*, defaults to `torch.float32`): + The torch dtype to use for the whole session. + """ + video_storage_device = video_storage_device if video_storage_device is not None else inference_device + inference_state_device = inference_state_device if inference_state_device is not None else inference_device + processing_device = processing_device if processing_device is not None else inference_device + pixel_values_video = None + video_height = None + video_width = None + if video is not None: + processed_video = self.video_processor(videos=video, device=processing_device, return_tensors="pt") + pixel_values_video = processed_video.pixel_values_videos[0] + video_height = processed_video.original_sizes[0][0] + video_width = processed_video.original_sizes[0][1] + inference_session = Sam2VideoInferenceSession( + video=pixel_values_video, + video_height=video_height, + video_width=video_width, + inference_device=inference_device, + video_storage_device=video_storage_device, + inference_state_device=inference_state_device, + dtype=dtype, + max_vision_features_cache_size=max_vision_features_cache_size, + ) + return inference_session + + def add_inputs_to_inference_session( + self, + inference_session: Sam2VideoInferenceSession, + frame_idx: int, + obj_ids: list[int] | int, + input_points: list[list[list[list[float]]]] | torch.Tensor | None = None, + input_labels: list[list[list[int]]] | torch.Tensor | None = None, + input_boxes: list[list[list[float]]] | torch.Tensor | None = None, + input_masks: np.ndarray | torch.Tensor | list[np.ndarray] | list[torch.Tensor] | None = None, + original_size: tuple[int, int] | None = None, + clear_old_inputs: bool = True, + ) -> Sam2VideoInferenceSession: + """ + Process new points, boxes, or masks for a video frame and add them to the inference session. + + Args: + inference_session (`Sam2VideoInferenceSession`): + The inference session for the video. + frame_idx (`int`): + The index of the frame to process. + obj_ids (`list[int]` or `int`): + The object ID(s) to associate with the points or box. + These can be any integers and can be reused later on to specify an object. + input_points (`list[list[list[list[float]]]]`, `torch.Tensor`, *optional*): + The points to add to the frame. + input_labels (`list[list[list[int]]]`, `torch.Tensor`, *optional*): + The labels for the points. + input_boxes (`list[list[list[float]]]`, `torch.Tensor`, *optional*): + The bounding boxes to add to the frame. + input_masks (`np.ndarray`, `torch.Tensor`, `list[np.ndarray]`, or `list[torch.Tensor]`, *optional*): + The mask(s) to add to the frame. + original_size (`tuple[int, int]`, *optional*): + The original size of the video. Provide when streaming. + clear_old_inputs (`bool`, *optional*, defaults to `True`): + Whether to clear old inputs for the object. + """ + + if isinstance(obj_ids, int): + obj_ids = [obj_ids] + + # Validate inputs + if (input_points is not None) != (input_labels is not None): + raise ValueError("points and labels must be provided together") + if input_points is None and input_boxes is None and input_masks is None: + raise ValueError("at least one of points, boxes, or masks must be provided as input") + if input_masks is not None and (input_points is not None or input_boxes is not None): + raise ValueError("masks cannot be provided together with points or boxes") + + if input_masks is not None: + return self.process_new_mask_for_video_frame(inference_session, frame_idx, obj_ids, input_masks) + else: + return self.process_new_points_or_boxes_for_video_frame( + inference_session, + frame_idx, + obj_ids, + input_points, + input_labels, + input_boxes, + original_size, + clear_old_inputs, + ) + + def process_new_points_or_boxes_for_video_frame( + self, + inference_session: Sam2VideoInferenceSession, + frame_idx: int, + obj_ids: list[int], + input_points: list[list[list[list[float]]]] | torch.Tensor | None = None, + input_labels: list[list[list[int]]] | torch.Tensor | None = None, + input_boxes: list[list[list[float]]] | torch.Tensor | None = None, + original_size: tuple[int, int] | None = None, + clear_old_inputs: bool = True, + ) -> Sam2VideoInferenceSession: + """ + Process new points or boxes for a video frame and add them to the inference session. + + Args: + inference_session (`Sam2VideoInferenceSession`): + The inference session for the video. + frame_idx (`int`): + The index of the frame to process. + obj_ids (`list[int]`): + The object ID(s) to associate with the points or box. + These can be any integers and can be reused later on to specify an object. + input_points (`list[list[list[list[float]]]]`, `torch.Tensor`, *optional*): + The points to add to the frame. + input_labels (`list[list[list[int]]]`, `torch.Tensor`, *optional*): + The labels for the points. + input_boxes (`list[list[list[float]]]`, `torch.Tensor`, *optional*): + The bounding boxes to add to the frame. + original_size (`tuple[int, int]`, *optional*): + The original size of the video. Provide when streaming. + clear_old_inputs (`bool`, *optional*, defaults to `True`): + Whether to clear old inputs for the object. + """ + if original_size is not None: + inference_session.video_height = original_size[0] + inference_session.video_width = original_size[1] + elif inference_session.video_height is None or inference_session.video_width is None: + raise ValueError("original_size must be provided when adding points or boxes on a first streamed frame") + + original_sizes = [[inference_session.video_height, inference_session.video_width]] + + encoded_inputs = self( + input_points=input_points, + input_labels=input_labels, + input_boxes=input_boxes, + original_sizes=original_sizes, + return_tensors="pt", + ) + input_points = encoded_inputs.get("input_points", None) + input_labels = encoded_inputs.get("input_labels", None) + input_boxes = encoded_inputs.get("input_boxes", None) + + if input_points is not None: + if input_points.shape[1] != len(obj_ids): + raise ValueError( + f"Number of object ids ({len(obj_ids)}) does not match number of points ({input_points.shape[1]})" + ) + else: + input_points = torch.zeros(1, len(obj_ids), 0, 2, dtype=torch.float32) + if input_labels is not None: + if input_labels.shape[1] != len(obj_ids): + raise ValueError( + f"Number of object ids ({len(obj_ids)}) does not match number of labels ({input_labels.shape[1]})" + ) + else: + input_labels = torch.zeros(1, len(obj_ids), 0, dtype=torch.int32) + if input_boxes is not None: + if input_boxes.shape[1] != len(obj_ids): + raise ValueError( + f"Number of object ids ({len(obj_ids)}) does not match number of boxes ({input_boxes.shape[1]})" + ) + + if input_boxes is not None: + if not clear_old_inputs: + raise ValueError( + "cannot add box without clearing old points, since " + "box prompt must be provided before any point prompt " + "(please use clear_old_points=True instead)" + ) + box_coords = input_boxes.reshape(1, -1, 2, 2) + box_labels = torch.tensor([2, 3], dtype=torch.int32).repeat(1, box_coords.shape[1], 1) + input_points = torch.cat([box_coords, input_points], dim=2) + input_labels = torch.cat([box_labels, input_labels], dim=2) + + for obj_id, idx in zip(obj_ids, range(len(obj_ids))): + obj_idx = inference_session.obj_id_to_idx(obj_id) + input_points_for_obj = input_points[:, idx, :, :].unsqueeze(1) + input_labels_for_obj = input_labels[:, idx, :].unsqueeze(1) + # Handle existing points + if not clear_old_inputs: + existing_points = inference_session.point_inputs_per_obj[obj_idx].get(frame_idx, None) + if existing_points is not None: + # Concatenate with existing points + input_points_for_obj = torch.cat( + [existing_points["point_coords"].to(input_points_for_obj.device), input_points_for_obj], dim=2 + ) + input_labels_for_obj = torch.cat( + [existing_points["point_labels"].to(input_labels_for_obj.device), input_labels_for_obj], dim=2 + ) + point_inputs = { + "point_coords": input_points_for_obj, + "point_labels": input_labels_for_obj, + } + + inference_session.add_point_inputs(obj_idx, frame_idx, point_inputs) + inference_session.remove_mask_inputs(obj_idx, frame_idx) # Clear any mask inputs + + inference_session.obj_with_new_inputs = obj_ids + + def process_new_mask_for_video_frame( + self, + inference_session: Sam2VideoInferenceSession, + frame_idx: int, + obj_ids: list[int], + input_masks: np.ndarray | torch.Tensor | list[np.ndarray] | list[torch.Tensor], + ): + """ + Add new mask to a frame and add them to the inference session. + + Args: + inference_session (`Sam2VideoInferenceSession`): + The inference session for the video. + frame_idx (`int`): + The index of the frame to process. + obj_ids (`list[int]`): + The object ID(s) to associate with the mask. + These can be any integers and can be reused later on to specify an object. + input_masks (`np.ndarray`, `torch.Tensor`, `list[np.ndarray]`, or `list[torch.Tensor]`): + The mask(s) to add to the frame. + """ + if not isinstance(input_masks, list): + input_masks = [input_masks] + if len(input_masks) != len(obj_ids): + raise ValueError( + f"Number of object ids ({len(obj_ids)}) does not match number of masks ({len(input_masks)})" + ) + + for obj_id, mask in zip(obj_ids, input_masks): + obj_idx = inference_session.obj_id_to_idx(obj_id) + + device = inference_session.inference_device + + # Process mask + if not isinstance(mask, torch.Tensor): + mask = torch.tensor(mask, dtype=torch.bool) + nb_dim = mask.dim() + if nb_dim > 4 or nb_dim < 2: + raise ValueError(f"Mask has an unsupported number of dimensions: {nb_dim}") + for i in range(4 - nb_dim): + mask = mask.unsqueeze(0) + + mask_H, mask_W = mask.shape[-2:] + mask_inputs_orig = mask.to(device) + mask_inputs_orig = mask_inputs_orig.float().to(device) + + # Resize mask if needed + if mask_H != self.target_size or mask_W != self.target_size: + mask_inputs = torch.nn.functional.interpolate( + mask_inputs_orig, + size=(self.target_size, self.target_size), + align_corners=False, + mode="bilinear", + antialias=True, + ) + mask_inputs = (mask_inputs >= 0.5).float() + else: + mask_inputs = mask_inputs_orig + + inference_session.add_mask_inputs(obj_idx, frame_idx, mask_inputs) + inference_session.remove_point_inputs(obj_idx, frame_idx) # Clear any point inputs + + inference_session.obj_with_new_inputs = obj_ids + + +class Sam2VideoLayerNorm(Sam2LayerNorm): + pass + + +class Sam2VideoPositionEmbeddingSine(Sam2SinePositionEmbedding): + pass + + +class Sam2VideoTwoWayAttentionBlock(Sam2TwoWayAttentionBlock): + pass + + +class Sam2VideoFeedForward(Sam2FeedForward): + pass + + +class Sam2VideoImageSegmentationOutput(Sam2ImageSegmentationOutput): + r""" + iou_scores (`torch.FloatTensor` of shape `(batch_size, point_batch_size, num_masks)`): + The Intersection over Union (IoU) scores of the predicted masks. + pred_masks (`torch.FloatTensor` of shape `(batch_size, point_batch_size, num_masks, height, width)`): + The predicted low-resolution masks. This is an alias for `low_res_masks`. These masks need to be post-processed + by the processor to be brought to the original image size. + object_score_logits (`torch.FloatTensor` of shape `(batch_size, point_batch_size, 1)`): + Logits for the object score, indicating if an object is present. + image_embeddings (`tuple(torch.FloatTensor)`): + The features from the FPN, which are used by the mask decoder. This is a tuple of `torch.FloatTensor` where each + tensor has shape `(batch_size, channels, height, width)`. + vision_hidden_states (`tuple(torch.FloatTensor)`, *optional*, returned when `output_hidden_states=True`): + Tuple of `torch.FloatTensor` (one for the output of each stage) of shape `(batch_size, height, width, hidden_size)`. + Hidden-states of the vision model at the output of each stage. + vision_attentions (`tuple(torch.FloatTensor)`, *optional*, returned when `output_attentions=True`): + Tuple of `torch.FloatTensor` (one for each layer) of shape `(batch_size, num_heads, sequence_length, sequence_length)`. + Attentions weights of the vision model. + mask_decoder_attentions (`tuple(torch.FloatTensor)`, *optional*, returned when `output_attentions=True`): + Tuple of `torch.FloatTensor` (one for each layer) of shape `(batch_size, num_heads, sequence_length, sequence_length)`. + Attentions weights of the mask decoder. + high_res_masks (`torch.FloatTensor` of shape `(batch_size, point_batch_size, num_masks, image_size, image_size)`, *optional*): + The predicted masks, upscaled to the original image size. Only used for Sam2VideoModel. + object_pointer (`torch.FloatTensor` of shape `(batch_size, point_batch_size, hidden_size)`, *optional*): + A tensor representing the object pointer, used for tracking in videos. Only used for Sam2VideoModel. + """ + + high_res_masks: torch.FloatTensor | None = None + object_pointer: torch.FloatTensor | None = None + + +@dataclass +@auto_docstring(custom_intro="Base class for the Sam2 model's output.") +class Sam2VideoSegmentationOutput(ModelOutput): + r""" + object_ids (`list[int]`, *optional*): + List of object IDs being tracked in the current frame. + pred_masks (`torch.FloatTensor` of shape `(batch_size, num_masks, height, width)`): + The predicted masks stored at the model's resolution. + object_score_logits (`torch.FloatTensor` of shape `(batch_size,)`, *optional*): + Logits for the object scores, indicating if objects are present. + frame_idx (`int`): + The frame index of the video. + """ + + object_ids: list[int] | None = None + pred_masks: torch.FloatTensor | None = None + object_score_logits: torch.FloatTensor | None = None + frame_idx: int | None = None + + +@auto_docstring +class Sam2VideoPreTrainedModel(PreTrainedModel): + config_class = Sam2VideoConfig + base_model_prefix = "sam2_video" + main_input_name = "pixel_values" + input_modalities = "video" + _supports_sdpa = True + _supports_flash_attn = True + _supports_attention_backend = True + + @torch.no_grad() + def _init_weights(self, module): + super()._init_weights(module) + if isinstance(module, Sam2VideoModel): + if module.no_memory_positional_encoding is not None: + init.zeros_(module.no_memory_positional_encoding) + if module.memory_temporal_positional_encoding is not None: + init.zeros_(module.memory_temporal_positional_encoding) + if module.no_object_pointer is not None: + init.zeros_(module.no_object_pointer) + if module.occlusion_spatial_embedding_parameter is not None: + init.zeros_(module.occlusion_spatial_embedding_parameter) + if isinstance(module, Sam2VideoMemoryFuserCXBlock): + if module.scale is not None: + init.zeros_(module.scale) + elif isinstance(module, Sam2VideoVisionRotaryEmbedding): + inv_freq = module.create_inv_freq() + init.copy_(module.rope_embeddings_cos, inv_freq.cos()) + init.copy_(module.rope_embeddings_sin, inv_freq.sin()) + elif isinstance(module, Sam2VideoPositionalEmbedding): + init.normal_(module.positional_embedding, std=module.scale) + + +class Sam2VideoVisionRotaryEmbedding(nn.Module): + """ + Vision Rotary Position Embedding for SAM2, following transformers library standards. + Supports 2D (axial) rotary embeddings for spatial dimensions. + """ + + def __init__(self, config: Sam2VideoConfig): + super().__init__() + self.dim = config.memory_attention_hidden_size // ( + config.memory_attention_downsample_rate * config.memory_attention_num_attention_heads + ) + # Ensure even dimension for proper axial splitting + if self.dim % 4 != 0: + raise ValueError("Dimension must be divisible by 4 for axial RoPE") + self.end_x, self.end_y = config.memory_attention_rope_feat_sizes + self.memory_attention_rope_theta = config.memory_attention_rope_theta + + # directly register the cos and sin embeddings as we have a fixed feature shape + inv_freq = self.create_inv_freq() + self.register_buffer("rope_embeddings_cos", inv_freq.cos(), persistent=False) + self.register_buffer("rope_embeddings_sin", inv_freq.sin(), persistent=False) + + @torch.no_grad() + def forward(self) -> tuple[torch.Tensor, torch.Tensor]: + # As the feature map size is fixed, we can just return the pre-computed embeddings. + return self.rope_embeddings_cos, self.rope_embeddings_sin + + def create_inv_freq(self): + freqs = 1.0 / ( + self.memory_attention_rope_theta ** (torch.arange(0, self.dim, 4)[: (self.dim // 4)].float() / self.dim) + ) + # Generate 2D position indices for axial rotary embedding + flattened_indices = torch.arange(self.end_x * self.end_y, dtype=torch.long) + x_positions = flattened_indices % self.end_x + y_positions = torch.div(flattened_indices, self.end_x, rounding_mode="floor") + freqs_x = torch.outer(x_positions, freqs).float() + freqs_y = torch.outer(y_positions, freqs).float() + inv_freq = torch.cat([freqs_x, freqs_y], dim=-1) + inv_freq = inv_freq.repeat_interleave(2, dim=-1) + return inv_freq + + +def rotate_pairwise(x): + """ + pairwise rotation of the hidden dims of the input. Differerent from Llama Half-Tensor Rotation. + + This is an optimized version of the following more explicit implementation: + ```python + x_rotated = torch.zeros_like(x, dtype=x.dtype, device=x.device) + x_rotated[..., ::2] = -x[..., 1::2] + x_rotated[..., 1::2] = x[..., ::2] + return x_rotated + ``` + """ + x = x.view(*x.shape[:-1], -1, 2) + x1, x2 = x.unbind(dim=-1) + x = torch.stack((-x2, x1), dim=-1) + return x.flatten(start_dim=-2) + + +# TODO: This leads to ~1e-07 max diff and ~1e-09 avg diff for q_embed and k_embed from the original implementation, most likely due to the use of complex tensors in the original implementation. +def apply_rotary_pos_emb_2d( + q: torch.Tensor, + k: torch.Tensor, + cos: torch.Tensor, + sin: torch.Tensor, + num_k_exclude_rope: int = 0, + repeat_freqs_k: bool = False, +) -> tuple[torch.Tensor, torch.Tensor]: + """ + Apply rotary position embedding to query and key tensors for vision models. + Follows the standard transformers library pattern. + + Args: + q: Query tensor of shape (..., seq_len, head_dim) + k: Key tensor of shape (..., seq_len, head_dim) + cos: Cosine position embedding of shape (seq_len, head_dim) + sin: Sine position embedding of shape (seq_len, head_dim) + repeat_freqs_k: Whether to repeat frequencies for keys (for cross-attention) + + Returns: + Rotated (q, k) tensors + """ + k_rot, k_pass = k[..., : k.shape[-2] - num_k_exclude_rope, :], k[..., k.shape[-2] - num_k_exclude_rope :, :] + q_embed = q.float() # force upscale to float32 as in the original implementation + q_embed = (q_embed * cos) + (rotate_pairwise(q_embed) * sin) + if k_rot.shape[-2] == 0: + # Handle case where keys might be empty due to dropout + return q_embed.type_as(q), torch.cat([k_rot, k_pass], dim=-2) + + # Handle key tensor - may need to repeat frequencies if different sequence length + if repeat_freqs_k and k_rot.shape[-2] != q.shape[-2]: + # Repeat cos/sin to match key sequence length + repeat_factor = k_rot.shape[-2] // q.shape[-2] + cos_k = cos.repeat(1, 1, repeat_factor, 1) + sin_k = sin.repeat(1, 1, repeat_factor, 1) + else: + cos_k = cos + sin_k = sin + + # Apply rotary embedding to keys + k_embed = k_rot.float() # force upscale to float32 as in the original implementation + k_embed = (k_embed * cos_k) + (rotate_pairwise(k_embed) * sin_k) + # Concatenate back to full shape + k_embed = torch.cat([k_embed.type_as(k), k_pass], dim=-2) + return q_embed.type_as(q), k_embed + + +class Sam2VideoRoPEAttention(nn.Module): + """Attention with rotary position encoding.""" + + def __init__( + self, + config: Sam2VideoConfig, + kv_in_dim: int | None = None, + rope_k_repeat=False, + ): + super().__init__() + self.config = config + self.hidden_size = config.memory_attention_hidden_size + self.internal_dim = self.hidden_size // config.memory_attention_downsample_rate + self.num_attention_heads = config.memory_attention_num_attention_heads + self.head_dim = self.internal_dim // config.memory_attention_num_attention_heads + self.scaling = self.head_dim**-0.5 + self.is_causal = False + + self.kv_in_dim = kv_in_dim if kv_in_dim is not None else self.hidden_size + + self.q_proj = nn.Linear(self.hidden_size, self.internal_dim) + self.k_proj = nn.Linear(self.kv_in_dim, self.internal_dim) + self.v_proj = nn.Linear(self.kv_in_dim, self.internal_dim) + self.o_proj = nn.Linear(self.internal_dim, self.hidden_size) + + self.rope_k_repeat = rope_k_repeat + self.dropout_p = config.memory_attention_rope_dropout + + def forward( + self, + query: torch.Tensor, + key: torch.Tensor, + value: torch.Tensor, + position_embeddings: tuple[torch.Tensor, torch.Tensor], + num_k_exclude_rope: int = 0, + **kwargs: Unpack[FlashAttentionKwargs], + ) -> Tensor: + # Input projections + batch_size, point_batch_size = query.shape[:2] + new_shape = (batch_size * point_batch_size, -1, self.num_attention_heads, self.head_dim) + + query = self.q_proj(query).view(*new_shape).transpose(1, 2) + key = self.k_proj(key).view(*new_shape).transpose(1, 2) + value = self.v_proj(value).view(*new_shape).transpose(1, 2) + + cos, sin = position_embeddings + # Apply rotary position encoding, excluding some keys if specified + query, key = apply_rotary_pos_emb_2d( + query, key, cos, sin, repeat_freqs_k=self.rope_k_repeat, num_k_exclude_rope=num_k_exclude_rope + ) + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, eager_attention_forward + ) + + attn_output, attn_weights = attention_interface( + self, + query, + key, + value, + attention_mask=None, + dropout=0.0 if not self.training else self.dropout_p, + scaling=self.scaling, + is_causal=self.is_causal, + **kwargs, + ) + attn_output = attn_output.reshape( + batch_size, point_batch_size, -1, self.num_attention_heads * self.head_dim + ).contiguous() + attn_output = self.o_proj(attn_output) + return attn_output, attn_weights + + +class Sam2VideoMemoryAttentionLayer(nn.Module): + def __init__(self, config: Sam2VideoConfig): + super().__init__() + hidden_size = config.memory_attention_hidden_size + self.self_attn = Sam2VideoRoPEAttention(config) + self.cross_attn_image = Sam2VideoRoPEAttention(config, kv_in_dim=64, rope_k_repeat=True) + + # Implementation of Feedforward model + self.linear1 = nn.Linear(hidden_size, config.memory_attention_feed_forward_hidden_size) + self.dropout = nn.Dropout(config.memory_attention_dropout) + self.linear2 = nn.Linear(config.memory_attention_feed_forward_hidden_size, hidden_size) + + self.layer_norm1 = nn.LayerNorm(hidden_size) + self.layer_norm2 = nn.LayerNorm(hidden_size) + self.layer_norm3 = nn.LayerNorm(hidden_size) + self.dropout1 = nn.Dropout(config.memory_attention_dropout) + self.dropout2 = nn.Dropout(config.memory_attention_dropout) + self.dropout3 = nn.Dropout(config.memory_attention_dropout) + + self.activation = ACT2FN[config.memory_attention_feed_forward_hidden_act] + + def forward( + self, + queries: Tensor, + keys: Tensor, + key_point_embedding: Tensor, + rope_position_embeddings: tuple[Tensor, Tensor], + num_k_exclude_rope: int = 0, + ) -> torch.Tensor: + # Self-Attention + query = self.layer_norm1(queries) + query, _ = self.self_attn(query=query, key=query, value=query, position_embeddings=rope_position_embeddings) + queries = queries + self.dropout1(query) + + # Cross-Attention + query = self.layer_norm2(queries) + query, _ = self.cross_attn_image( + query=query, + key=keys + key_point_embedding, + value=keys, + position_embeddings=rope_position_embeddings, + num_k_exclude_rope=num_k_exclude_rope, + ) + queries = queries + self.dropout2(query) + # MLP + query = self.layer_norm3(queries) + query = self.linear2(self.dropout(self.activation(self.linear1(query)))) + queries = queries + self.dropout3(query) + return queries + + +class Sam2VideoMemoryAttention(nn.Module): + def __init__(self, config: Sam2VideoConfig): + super().__init__() + self.layers = nn.ModuleList( + [Sam2VideoMemoryAttentionLayer(config) for _ in range(config.memory_attention_num_layers)] + ) + self.layer_norm = nn.LayerNorm(config.memory_attention_hidden_size) + self.rotary_emb = Sam2VideoVisionRotaryEmbedding(config=config) + + def forward( + self, + current_vision_features: torch.Tensor, + memory: torch.Tensor, + current_vision_position_embeddings: Tensor | None = None, + memory_posision_embeddings: Tensor | None = None, + num_object_pointer_tokens: int = 0, + ): + """ + Args: + current_vision_features (`torch.FloatTensor`): + The current vision features used for self-attention. + memory (`torch.FloatTensor`): + The memory features used for cross-attention. + current_vision_position_embeddings (`torch.FloatTensor`, *optional*): + The position embeddings for the current vision features. + memory_posision_embeddings (`torch.FloatTensor`, *optional*): + The position embeddings for the memory features. + num_object_pointer_tokens (`int`, *optional*, defaults to 0): + The number of object pointer tokens. + """ + output = current_vision_features + if current_vision_position_embeddings is not None: + output = output + 0.1 * current_vision_position_embeddings + + # Convert to batch first + output = output.transpose(0, 1) + memory = memory.transpose(0, 1).unsqueeze(1) + memory_posision_embeddings = memory_posision_embeddings.transpose(0, 1).unsqueeze(1) + rope_position_embeddings = self.rotary_emb() + for layer in self.layers: + output = layer( + queries=output.unsqueeze(1) if output.ndim == 3 else output, + keys=memory, + key_point_embedding=memory_posision_embeddings, + rope_position_embeddings=rope_position_embeddings, + num_k_exclude_rope=num_object_pointer_tokens, + ) + + normed_output = self.layer_norm(output) + + # Convert back to seq first + normed_output = normed_output.transpose(0, 1) + + return normed_output + + +# Lightly adapted from ConvNext (https://github.com/facebookresearch/ConvNeXt) +class Sam2VideoMemoryFuserCXBlock(GradientCheckpointingLayer): + def __init__(self, config: Sam2VideoConfig): + super().__init__() + self.depthwise_conv = nn.Conv2d( + config.memory_fuser_embed_dim, + config.memory_fuser_embed_dim, + kernel_size=config.memory_fuser_kernel_size, + padding=config.memory_fuser_padding, + groups=config.memory_fuser_embed_dim, + ) # depthwise conv + self.layer_norm = Sam2VideoLayerNorm(config.memory_fuser_embed_dim, eps=1e-6, data_format="channels_first") + self.activation = ACT2FN[config.memory_fuser_hidden_act] + self.pointwise_conv1 = nn.Linear( + config.memory_fuser_embed_dim, config.memory_fuser_intermediate_dim + ) # pointwise/1x1 convs, implemented with linear layers + self.pointwise_conv2 = nn.Linear(config.memory_fuser_intermediate_dim, config.memory_fuser_embed_dim) + self.scale = nn.Parameter( + config.memory_fuser_layer_scale_init_value * torch.ones(config.memory_fuser_embed_dim), + requires_grad=True, + ) + + def forward(self, hidden_states): + input = hidden_states + hidden_states = self.depthwise_conv(hidden_states) + hidden_states = self.layer_norm(hidden_states) + hidden_states = hidden_states.permute(0, 2, 3, 1) # (N, C, H, W) -> (N, H, W, C) + hidden_states = self.pointwise_conv1(hidden_states) + hidden_states = self.activation(hidden_states) + hidden_states = self.pointwise_conv2(hidden_states) + hidden_states = self.scale * hidden_states + hidden_states = hidden_states.permute(0, 3, 1, 2) # (N, H, W, C) -> (N, C, H, W) + + hidden_states = input + hidden_states + return hidden_states + + +class Sam2VideoMemoryFuser(nn.Module): + def __init__(self, config: Sam2VideoConfig): + super().__init__() + self.layers = nn.ModuleList( + [Sam2VideoMemoryFuserCXBlock(config) for _ in range(config.memory_fuser_num_layers)] + ) + + def forward(self, hidden_states): + # normally hidden_states: (N, C, H, W) + for layer in self.layers: + hidden_states = layer(hidden_states) + return hidden_states + + +class Sam2VideoMaskDownSamplerLayer(nn.Module): + def __init__(self, config: Sam2VideoConfig, in_channels: int, out_channels: int): + super().__init__() + self.conv = nn.Conv2d( + in_channels, + out_channels, + kernel_size=config.mask_downsampler_kernel_size, + stride=config.mask_downsampler_stride, + padding=config.mask_downsampler_padding, + ) + self.layer_norm = Sam2VideoLayerNorm(out_channels, eps=1e-6, data_format="channels_first") + self.activation = ACT2FN[config.mask_downsampler_hidden_act] + + def forward(self, x): + return self.activation(self.layer_norm(self.conv(x))) + + +class Sam2VideoMaskDownSampler(nn.Module): + """ + Progressively downsample a mask by total_stride, each time by stride. + Note that LayerNorm is applied per *token*, like in ViT. + + With each downsample (by a factor stride**2), channel capacity increases by the same factor. + In the end, we linearly project to embed_dim channels. + """ + + def __init__(self, config: Sam2VideoConfig): + super().__init__() + + num_layers = int(math.log2(config.mask_downsampler_total_stride) // math.log2(config.mask_downsampler_stride)) + + self.layers = nn.ModuleList() + self.activation = ACT2FN[config.mask_downsampler_hidden_act] + mask_in_chans, mask_out_chans = 1, 1 + for _ in range(num_layers): + mask_out_chans = mask_in_chans * (config.mask_downsampler_stride**2) + self.layers.append(Sam2VideoMaskDownSamplerLayer(config, mask_in_chans, mask_out_chans)) + mask_in_chans = mask_out_chans + + self.final_conv = nn.Conv2d(mask_out_chans, config.mask_downsampler_embed_dim, kernel_size=1) + + def forward(self, x): + for layer in self.layers: + x = layer(x) + x = self.final_conv(x) + return x + + +class Sam2VideoMemoryEncoder(nn.Module): + def __init__(self, config: Sam2VideoConfig): + super().__init__() + + hidden_size = config.memory_encoder_hidden_size + output_channels = config.memory_encoder_output_channels + self.mask_downsampler = Sam2VideoMaskDownSampler(config) + self.feature_projection = nn.Conv2d(hidden_size, hidden_size, kernel_size=1) + self.memory_fuser = Sam2VideoMemoryFuser(config) + self.position_encoding = Sam2VideoPositionEmbeddingSine(num_pos_feats=output_channels // 2, normalize=True) + self.projection = nn.Conv2d(hidden_size, output_channels, kernel_size=1) + + def forward( + self, + vision_features: torch.Tensor, + masks: torch.Tensor, + ) -> tuple[torch.Tensor, torch.Tensor]: + ## Process masks + masks = self.mask_downsampler(masks) + ## Fuse pixel_features and downsampled masks + + vision_features = self.feature_projection(vision_features) + vision_features = vision_features + masks + vision_features = self.memory_fuser(vision_features) + vision_features = self.projection(vision_features) + + vision_pos_enc = self.position_encoding(vision_features.shape, vision_features.device, vision_features.dtype) + + return vision_features, vision_pos_enc + + +class Sam2VideoPositionalEmbedding(Sam2PositionalEmbedding): + pass + + +# a large negative value as a placeholder score for missing objects +NO_OBJ_SCORE = -1024.0 + + +def get_1d_sine_pe(pos_inds, dim, temperature=10000): + """ + Get 1D sine positional embedding as in the original Transformer paper. + """ + pe_dim = dim // 2 + dim_t = torch.arange(pe_dim, dtype=torch.float32, device=pos_inds.device) + dim_t = temperature ** (2 * (dim_t // 2) / pe_dim) + + pos_embed = pos_inds.unsqueeze(-1) / dim_t + pos_embed = torch.cat([pos_embed.sin(), pos_embed.cos()], dim=-1) + return pos_embed + + +@auto_docstring +class Sam2VideoModel(Sam2Model): + input_modalities = ("video", "text") + _keys_to_ignore_on_load_unexpected = [] + _can_record_outputs = {"mask_decoder_attentions": OutputRecorder(Sam2VideoTwoWayAttentionBlock, index=2)} + + def __init__(self, config: Sam2VideoConfig): + super().__init__(config) + self.config = config + # For video sequence inference + self.image_size = config.image_size + self.memory_attention = Sam2VideoMemoryAttention(config) + self.memory_encoder = Sam2VideoMemoryEncoder(config) + self.no_memory_positional_encoding = torch.nn.Parameter( + torch.zeros(1, 1, config.vision_config.fpn_hidden_size) + ) + self.mem_dim = config.memory_encoder_output_channels + self.num_maskmem = config.num_maskmem # Number of memories accessible + # Temporal encoding of the memories + self.memory_temporal_positional_encoding = torch.nn.Parameter( + torch.zeros(self.num_maskmem, 1, 1, self.mem_dim) + ) + + self.no_object_pointer = torch.nn.Parameter(torch.zeros(1, self.hidden_dim)) + # A conv layer to downsample the mask prompt to stride 4 (the same stride as + # low-res SAM mask logits) and to change its scales from 0~1 to SAM logit scale, + # so that it can be fed into the SAM mask decoder to generate a pointer. + self.mask_downsample = torch.nn.Conv2d(1, 1, kernel_size=4, stride=4) + # a feedforward layer on SAM output tokens to turn them into object pointers + self.object_pointer_proj = Sam2VideoFeedForward(self.hidden_dim, self.hidden_dim, self.hidden_dim, 3) + + if self.config.enable_temporal_pos_encoding_for_object_pointers: + # a linear projection on temporal positional encoding in object pointers to + # avoid potential interference with spatial positional encoding + self.temporal_positional_encoding_projection_layer = torch.nn.Linear(self.hidden_dim, self.mem_dim) + else: + self.temporal_positional_encoding_projection_layer = torch.nn.Identity() + + self.occlusion_spatial_embedding_parameter = None # compatibility with Sam2 + if config.enable_occlusion_spatial_embedding: + self.occlusion_spatial_embedding_parameter = torch.nn.Parameter(torch.zeros(1, self.mem_dim)) + + self.post_init() + + @torch.no_grad() + def get_prompt_embeddings( + self, + input_points: torch.FloatTensor | None = None, + input_labels: torch.LongTensor | None = None, + input_boxes: torch.FloatTensor | None = None, + input_masks: torch.LongTensor | None = None, + ) -> tuple[torch.Tensor, torch.Tensor]: + r""" + Returns the prompt embeddings by passing the input points, labels, boxes and masks through the prompt encoder. + + Args: + input_points (`torch.FloatTensor` of shape `(batch_size, point_batch_size, num_points_per_image, 2)`): + Optional input points for the prompt encoder. The padding of the point is automatically done by the + processor. `point_batch_size` refers to the number of masks that we want the model to predict per + point. The model will output `point_batch_size` times 3 masks in total. + input_labels (`torch.LongTensor` of shape `(batch_size, point_batch_size, num_points_per_image)`): + Optional input labels for the prompt encoder. The padding of the labels is automatically done by the + processor, or can be fed by the user. + input_boxes (`torch.FloatTensor` of shape `(batch_size, num_boxes_per_image, 4)`): + Optional input boxes for the prompt encoder. The padding of the boxes is automatically done by the + processor. users can also pass manually the input boxes. + input_masks (`torch.LongTensor` of shape `(batch_size, image_size, image_size)`): + Optional input masks for the prompt encoder. + """ + prompt_output = self.prompt_encoder( + input_points=input_points, + input_labels=input_labels, + input_boxes=input_boxes, + input_masks=input_masks, + ) + return prompt_output + + def _prepare_vision_features( + self, + inference_session: Sam2VideoInferenceSession, + frame_idx: int, + batch_size: int, + ) -> tuple[torch.Tensor, list[torch.Tensor]]: + """Prepare vision features for a frame.""" + + # Check if features are cached + if cached_features := inference_session.cache.get_vision_features(frame_idx): + vision_feats = cached_features["vision_feats"] + vision_pos_embeds = cached_features["vision_pos_embeds"] + else: + # Compute features using image encoder + image_batch = inference_session.get_frame(frame_idx).unsqueeze(0) # Add batch dimension + image_outputs = self.get_image_features(image_batch, return_dict=True) + vision_feats = image_outputs.fpn_hidden_states + vision_pos_embeds = image_outputs.fpn_position_encoding + # Cache features + inference_session.cache.cache_vision_features( + frame_idx, {"vision_feats": vision_feats, "vision_pos_embeds": vision_pos_embeds} + ) + + # Expand to batch size if needed + if batch_size > 1: + vision_feats = vision_feats.expand(batch_size, -1, -1, -1) + vision_pos_embeds = [pe.expand(batch_size, -1, -1, -1) for pe in vision_pos_embeds] + + return vision_feats, vision_pos_embeds + + def _single_frame_forward( + self, + pixel_values: torch.FloatTensor | None = None, + input_points: torch.FloatTensor | None = None, + input_labels: torch.LongTensor | None = None, + input_boxes: torch.FloatTensor | None = None, + input_masks: torch.LongTensor | None = None, + image_embeddings: torch.FloatTensor | None = None, + multimask_output: bool = True, + attention_similarity: torch.FloatTensor | None = None, + target_embedding: torch.FloatTensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> Sam2VideoImageSegmentationOutput: + """ + input_points (`torch.FloatTensor` of shape `(batch_size, num_points, 2)`): + Input 2D spatial points, this is used by the prompt encoder to encode the prompt. Generally yields to much + better results. The points can be obtained by passing a list of list of list to the processor that will + create corresponding `torch` tensors of dimension 4. The first dimension is the image batch size, the + second dimension is the point batch size (i.e. how many segmentation masks do we want the model to predict + per input point), the third dimension is the number of points per segmentation mask (it is possible to pass + multiple points for a single mask), and the last dimension is the x (vertical) and y (horizontal) + coordinates of the point. If a different number of points is passed either for each image, or for each + mask, the processor will create "PAD" points that will correspond to the (0, 0) coordinate, and the + computation of the embedding will be skipped for these points using the labels. + input_labels (`torch.LongTensor` of shape `(batch_size, point_batch_size, num_points)`): + Input labels for the points, this is used by the prompt encoder to encode the prompt. According to the + official implementation, there are 3 types of labels + + - `1`: the point is a point that contains the object of interest + - `0`: the point is a point that does not contain the object of interest + - `-1`: the point corresponds to the background + + We added the label: + + - `-10`: the point is a padding point, thus should be ignored by the prompt encoder + + The padding labels should be automatically done by the processor. + input_boxes (`torch.FloatTensor` of shape `(batch_size, num_boxes, 4)`): + Input boxes for the points, this is used by the prompt encoder to encode the prompt. Generally yields to + much better generated masks. The boxes can be obtained by passing a list of list of list to the processor, + that will generate a `torch` tensor, with each dimension corresponding respectively to the image batch + size, the number of boxes per image and the coordinates of the top left and bottom right point of the box. + In the order (`x1`, `y1`, `x2`, `y2`): + + - `x1`: the x coordinate of the top left point of the input box + - `y1`: the y coordinate of the top left point of the input box + - `x2`: the x coordinate of the bottom right point of the input box + - `y2`: the y coordinate of the bottom right point of the input box + input_masks (`torch.FloatTensor` of shape `(batch_size, image_size, image_size)`): + SAM model also accepts segmentation masks as input. The mask will be embedded by the prompt encoder to + generate a corresponding embedding, that will be fed later on to the mask decoder. These masks needs to be + manually fed by the user, and they need to be of shape (`batch_size`, `image_size`, `image_size`). + image_embeddings (`torch.FloatTensor` of shape `(batch_size, output_channels, window_size, window_size)`): + Image embeddings, this is used by the mask decoder to generate masks and iou scores. For more memory + efficient computation, users can first retrieve the image embeddings using the `get_image_embeddings` + method, and then feed them to the `forward` method instead of feeding the `pixel_values`. + multimask_output (`bool`, *optional*): + In the original implementation and paper, the model always outputs 3 masks per image (or per point / per + bounding box if relevant). However, it is possible to just output a single mask, that corresponds to the + "best" mask, by specifying `multimask_output=False`. + attention_similarity (`torch.FloatTensor`, *optional*): + Attention similarity tensor, to be provided to the mask decoder for target-guided attention in case the + model is used for personalization as introduced in [PerSAM](https://huggingface.co/papers/2305.03048). + target_embedding (`torch.FloatTensor`, *optional*): + Embedding of the target concept, to be provided to the mask decoder for target-semantic prompting in case + the model is used for personalization as introduced in [PerSAM](https://huggingface.co/papers/2305.03048). + """ + if not ((pixel_values is None) ^ (image_embeddings is None)): + raise ValueError("Exactly one of pixel_values or image_embeddings must be provided.") + if input_points is not None and input_boxes is not None: + if input_points.shape[1] != input_boxes.shape[1]: + raise ValueError( + f"You should provide as many bounding boxes as input points per box. Got {input_points.shape[1]} and {input_boxes.shape[1]}." + ) + elif input_points is not None: + num_objects = input_points.shape[1] + elif input_boxes is not None: + num_objects = input_boxes.shape[1] + elif input_masks is not None: + num_objects = input_masks.shape[1] + else: + num_objects = 1 + + image_positional_embeddings = self.get_image_wide_positional_embeddings() + # repeat with batch size + batch_size = pixel_values.shape[0] if pixel_values is not None else image_embeddings[-1].shape[0] + image_positional_embeddings = image_positional_embeddings.repeat(batch_size, 1, 1, 1) + + vision_attentions = None + vision_hidden_states = None + + if pixel_values is not None: + image_outputs = self.get_image_features(pixel_values, return_dict=True, **kwargs) + feature_maps = image_outputs.fpn_hidden_states + vision_hidden_states = image_outputs.hidden_states + vision_attentions = image_outputs.attentions + + # add no memory embedding to the last feature map + feature_maps[-1] = feature_maps[-1] + self.no_memory_embedding + + # reshape feature maps to the same shape as the backbone feature sizes + image_embeddings = [ + feat.permute(1, 2, 0).view(batch_size, -1, *feat_size) + for feat, feat_size in zip(feature_maps, self.backbone_feature_sizes) + ] + + if input_points is not None and input_labels is None: + input_labels = torch.ones_like(input_points[:, :, :, 0], dtype=torch.int, device=input_points.device) + + if input_points is None and input_boxes is None: + # If no points are provide, pad with an empty point (with label -1) + input_points = torch.zeros( + batch_size, 1, 1, 2, dtype=image_embeddings[-1].dtype, device=image_embeddings[-1].device + ) + input_labels = -torch.ones(batch_size, 1, 1, dtype=torch.int32, device=image_embeddings[-1].device) + + if input_masks is not None: + # If mask_inputs is provided, downsize it into low-res mask input if needed + # and feed it as a dense mask prompt into the SAM mask encoder + if input_masks.shape[-2:] != self.prompt_encoder.mask_input_size: + input_masks = F.interpolate( + input_masks.float(), + size=self.prompt_encoder.mask_input_size, + align_corners=False, + mode="bilinear", + antialias=True, # use antialias for downsampling + ).to(input_masks.dtype) + + sparse_embeddings, dense_embeddings = self.prompt_encoder( + input_points=input_points, + input_labels=input_labels, + input_boxes=input_boxes, + input_masks=input_masks, + ) + low_res_multimasks, iou_scores, sam_output_tokens, object_score_logits = self.mask_decoder( + image_embeddings=image_embeddings[-1], + image_positional_embeddings=image_positional_embeddings, + sparse_prompt_embeddings=sparse_embeddings, + dense_prompt_embeddings=dense_embeddings, + multimask_output=multimask_output, + high_resolution_features=image_embeddings[:-1], + attention_similarity=attention_similarity, + target_embedding=target_embedding, + **kwargs, + ) + + is_obj_appearing = object_score_logits > 0 + # Mask used for spatial memories is always a *hard* choice between obj and no obj, + # consistent with the actual mask prediction + low_res_multimasks = torch.where( + is_obj_appearing[:, None, None], + low_res_multimasks, + NO_OBJ_SCORE, + ) + + # convert masks from possibly bfloat16 (or float16) to float32 + # (older PyTorch versions before 2.1 don't support `interpolate` on bf16) + high_res_multimasks = ( + F.interpolate( + low_res_multimasks.squeeze(1).float(), + size=(self.image_size, self.image_size), + mode="bilinear", + align_corners=False, + ) + .unsqueeze(1) + .to(low_res_multimasks.dtype) + ) + sam_output_token = sam_output_tokens[:, :, 0] + if multimask_output: + # take the best mask prediction (with the highest IoU estimation) + best_iou_inds = torch.argmax(iou_scores, dim=-1) + batch_inds = torch.arange(batch_size, device=high_res_multimasks.device) + object_batch_inds = torch.arange(num_objects, device=high_res_multimasks.device) + low_res_masks = low_res_multimasks[batch_inds, object_batch_inds, best_iou_inds] + high_res_masks = high_res_multimasks[batch_inds, object_batch_inds, best_iou_inds] + if sam_output_tokens.size(2) > 1: + sam_output_token = sam_output_tokens[batch_inds, object_batch_inds, best_iou_inds] + else: + low_res_masks, high_res_masks = low_res_multimasks[:, :, 0], high_res_multimasks[:, :, 0] + + # Extract object pointer from the SAM output token (with occlusion handling) + object_pointer = self.object_pointer_proj(sam_output_token) + lambda_is_obj_appearing = is_obj_appearing.to(object_pointer.dtype) + + object_pointer = lambda_is_obj_appearing * object_pointer + object_pointer = object_pointer + (1 - lambda_is_obj_appearing) * self.no_object_pointer + + return Sam2VideoImageSegmentationOutput( + iou_scores=iou_scores, + pred_masks=low_res_masks, + high_res_masks=high_res_masks, + object_pointer=object_pointer, + object_score_logits=object_score_logits, + image_embeddings=image_embeddings, + vision_hidden_states=vision_hidden_states, + vision_attentions=vision_attentions, + ) + + def _use_mask_as_output( + self, + backbone_features: torch.Tensor, + high_res_features: list[torch.Tensor], + mask_inputs: torch.Tensor, + ) -> Sam2VideoImageSegmentationOutput: + """ + Directly turn binary `mask_inputs` into a output mask logits without using SAM. + (same input and output shapes as in forward above). + """ + # Use -10/+20 as logits for neg/pos pixels (very close to 0/1 in prob after sigmoid). + out_scale, out_bias = 20.0, -10.0 # sigmoid(-10.0)=4.5398e-05 + mask_inputs_float = mask_inputs.to(backbone_features[0].dtype) + + # Ensure mask is at self.image_size resolution for consistency + if mask_inputs_float.shape[-2:] != (self.image_size, self.image_size): + mask_inputs_float = F.interpolate( + mask_inputs_float.float(), + size=(self.image_size, self.image_size), + align_corners=False, + mode="bilinear", + antialias=True, + ).to(mask_inputs.dtype) + + high_res_masks = mask_inputs_float * out_scale + out_bias + low_res_masks = F.interpolate( + high_res_masks.float(), + size=self.prompt_encoder.mask_input_size, + align_corners=False, + mode="bilinear", + antialias=True, # use antialias for downsampling + ).to(backbone_features[0].dtype) + # a dummy IoU prediction of all 1's under mask input + iou_scores = mask_inputs.new_ones(mask_inputs.size(0), 1).to(backbone_features[0].dtype) + # produce an object pointer using the SAM decoder from the mask input + object_pointer = self._single_frame_forward( + input_masks=self.mask_downsample(mask_inputs_float.to(backbone_features[0].dtype)), + image_embeddings=high_res_features + [backbone_features], + ).object_pointer + # In this method, we are treating mask_input as output, e.g. using it directly to create spatial mem; + # Below, we follow the same design axiom to use mask_input to decide if obj appears or not instead of relying + # on the object_scores from the SAM decoder. + is_obj_appearing = torch.any(mask_inputs.flatten(1).float() > 0.0, dim=1) + is_obj_appearing = is_obj_appearing[..., None] + lambda_is_obj_appearing = is_obj_appearing.to(backbone_features[0].dtype) + object_score_logits = out_scale * lambda_is_obj_appearing + out_bias + object_pointer = lambda_is_obj_appearing * object_pointer + object_pointer = object_pointer + (1 - lambda_is_obj_appearing) * self.no_object_pointer + return Sam2VideoImageSegmentationOutput( + iou_scores=iou_scores, + pred_masks=low_res_masks, + high_res_masks=high_res_masks, + object_pointer=object_pointer, + object_score_logits=object_score_logits.unsqueeze(-1), + image_embeddings=high_res_features + [backbone_features], + ) + + def _select_closest_cond_frames(self, frame_idx, cond_frame_outputs, max_cond_frame_num): + """ + Select up to `max_cond_frame_num` conditioning frames from `cond_frame_outputs` + that are temporally closest to the current frame at `frame_idx`. Here, we take + - a) the closest conditioning frame before `frame_idx` (if any); + - b) the closest conditioning frame after `frame_idx` (if any); + - c) any other temporally closest conditioning frames until reaching a total + of `max_cond_frame_num` conditioning frames. + + Outputs: + - selected_outputs: selected items (keys & values) from `cond_frame_outputs`. + - unselected_outputs: items (keys & values) not selected in `cond_frame_outputs`. + """ + if max_cond_frame_num == -1 or len(cond_frame_outputs) <= max_cond_frame_num: + selected_outputs = cond_frame_outputs + unselected_outputs = {} + else: + selected_outputs = {} + # the closest conditioning frame before `frame_idx` (if any) + idx_before = max((t for t in cond_frame_outputs if t < frame_idx), default=None) + if idx_before is not None: + selected_outputs[idx_before] = cond_frame_outputs[idx_before] + + # the closest conditioning frame after `frame_idx` (if any) + idx_after = min((t for t in cond_frame_outputs if t >= frame_idx), default=None) + if idx_after is not None: + selected_outputs[idx_after] = cond_frame_outputs[idx_after] + + # add other temporally closest conditioning frames until reaching a total + # of `max_cond_frame_num` conditioning frames. + num_remain = max_cond_frame_num - len(selected_outputs) + inds_remain = sorted( + (t for t in cond_frame_outputs if t not in selected_outputs), + key=lambda x: abs(x - frame_idx), + )[:num_remain] + selected_outputs.update((t, cond_frame_outputs[t]) for t in inds_remain) + unselected_outputs = {t: v for t, v in cond_frame_outputs.items() if t not in selected_outputs} + + return selected_outputs, unselected_outputs + + def _gather_memory_frame_outputs( + self, + inference_session: Sam2VideoInferenceSession, + obj_idx: int, + frame_idx: int, + track_in_reverse_time: bool = False, + ) -> list[tuple[int, dict]]: + """ + Get memory frames from conditioning and non-conditioning outputs. + + Returns: + List of (relative_temporal_offset, output_data) tuples. + """ + temporal_positions_and_previous_outputs = [] + + # Add conditioning frame outputs (limited by max_cond_frame_num) + conditioning_outputs = inference_session.output_dict_per_obj[obj_idx]["cond_frame_outputs"] + if not conditioning_outputs: + raise ValueError( + "maskmem_features in conditioning outputs cannot be empty when not is_initial_conditioning_frame" + ) + conditioning_outputs, unselected_conditioning_outputs = self._select_closest_cond_frames( + frame_idx, conditioning_outputs, max_cond_frame_num=self.config.max_cond_frame_num + ) + + # Store (temporal_position, output_data) tuples + temporal_positions_and_previous_outputs = [(0, out) for out in conditioning_outputs.values()] + + # Add non-conditioning memory frames (up to self.num_maskmem - 1) + # These are typically frames tracked by the model without direct user input. + # Frames are selected with a stride, prioritizing the most recent ones. Here we only support stride = 1 for simplicity. + for relative_temporal_offset in range(self.num_maskmem - 1, 0, -1): + # relative_temporal_offset: how many frames before (or after if reversing) the current frame + if not track_in_reverse_time: + previous_frame_idx = frame_idx - relative_temporal_offset + else: + previous_frame_idx = frame_idx + relative_temporal_offset + + # check if the output is already stored without using get_output to avoid unnecessary memory transfers between CPU and GPU + output_data = inference_session.output_dict_per_obj[obj_idx]["non_cond_frame_outputs"].get( + previous_frame_idx, unselected_conditioning_outputs.get(previous_frame_idx, None) + ) + + temporal_positions_and_previous_outputs.append((relative_temporal_offset, output_data)) + + return temporal_positions_and_previous_outputs + + def _build_memory_attention_inputs( + self, + temporal_positions_and_previous_outputs: list[tuple[int, dict]], + device: torch.device, + ) -> tuple[list[torch.Tensor], list[torch.Tensor]]: + """ + Concatenate memory features and positional embeddings from previous frames. + + Returns: + Tuple of (memories_to_concatenate, memory_positional_embeddings_to_concatenate). + """ + memories_to_concatenate = [] + memory_positional_embeddings_to_concatenate = [] + + for relative_temporal_offset, prev_output_data in temporal_positions_and_previous_outputs: + if prev_output_data is None: + continue # Skip if no output data for this temporal position (e.g., padding frames) + + # Load memory features (potentially from CPU to GPU) + # Features are flattened: (Batch, Channels, H, W) -> (H*W, Batch, Channels) + memory_features = prev_output_data["maskmem_features"].to(device, non_blocking=True) + memories_to_concatenate.append(memory_features) + + # Spatial positional encoding (potentially from CPU to GPU) + spatial_memory_pos_embed = prev_output_data["maskmem_pos_enc"].to(device, non_blocking=True) + + # Add temporal positional encoding + # self.memory_temporal_positional_encoding shape: (NumMaskMem, 1, 1, MemDim) + combined_memory_pos_embed = ( + spatial_memory_pos_embed + self.memory_temporal_positional_encoding[relative_temporal_offset - 1] + ) + memory_positional_embeddings_to_concatenate.append(combined_memory_pos_embed) + + return memories_to_concatenate, memory_positional_embeddings_to_concatenate + + def _get_object_pointers( + self, + inference_session: Sam2VideoInferenceSession, + obj_idx: int, + frame_idx: int, + num_total_frames: int, + device: torch.device, + track_in_reverse_time: bool = False, + streaming: bool = False, + ) -> tuple[list[int], list[torch.Tensor], int]: + """ + Get object pointers and their positional embeddings from past frames. + + Returns: + Tuple of (temporal_offsets, pointer_tokens, max_object_pointers_to_use). + """ + temporal_position_sign_multiplier = -1 if track_in_reverse_time else 1 + + # Determine max object pointers to use + if streaming: + max_object_pointers_to_use = self.config.max_object_pointers_in_encoder + else: + max_object_pointers_to_use = min(num_total_frames, self.config.max_object_pointers_in_encoder) + + temporal_offsets: list[int] = [] + pointer_tokens: list[torch.Tensor] = [] + + # Add object pointers from selected conditioning frames + # Optionally, only include pointers from past frames during evaluation + conditioning_outputs = inference_session.output_dict_per_obj[obj_idx]["cond_frame_outputs"] + eligible_conditioning_outputs = conditioning_outputs + if not self.training: + eligible_conditioning_outputs = { + temporal_idx: out + for temporal_idx, out in conditioning_outputs.items() + if (temporal_idx >= frame_idx if track_in_reverse_time else temporal_idx <= frame_idx) + } + + for temporal_idx, out_data in eligible_conditioning_outputs.items(): + temporal_difference = (frame_idx - temporal_idx) * temporal_position_sign_multiplier + temporal_offsets.append(temporal_difference) + pointer_tokens.append(out_data["object_pointer"].to(device)) + + # Add object pointers from non-conditioning frames (up to max_object_pointers_to_use - 1) + for t_diff_offset in range(1, max_object_pointers_to_use): + ref_frame_idx = frame_idx + t_diff_offset if track_in_reverse_time else frame_idx - t_diff_offset + if ref_frame_idx < 0 or ( + not streaming and num_total_frames is not None and ref_frame_idx >= num_total_frames + ): + break # Stop if frame index is out of bounds + + # check if the output is already stored without using get_output to avoid unnecessary memory transfers between CPU and GPU + out_data = inference_session.output_dict_per_obj[obj_idx]["non_cond_frame_outputs"].get( + ref_frame_idx, None + ) + if out_data is not None: + temporal_offsets.append(t_diff_offset) + pointer_tokens.append(out_data["object_pointer"].to(device)) + + return temporal_offsets, pointer_tokens, max_object_pointers_to_use + + def _process_object_pointers( + self, + temporal_offsets: list[int], + pointer_tokens: list[torch.Tensor], + max_object_pointers_to_use: int, + batch_size: int, + num_channels: int, + device: torch.device, + ) -> tuple[torch.Tensor, torch.Tensor]: + """ + Process object pointers and compute their positional embeddings. + + Returns: + Tuple of (object_pointers, object_pointers_pos_embed). + """ + if not pointer_tokens: + return None, None + + # Stack object pointers: List of (Batch, Channels) -> (SeqLen_ptr, Batch, Channels) + object_pointers = torch.stack(pointer_tokens, dim=0) + + if self.config.enable_temporal_pos_encoding_for_object_pointers: + max_temporal_diff = float(max_object_pointers_to_use - 1) + # Determine dimensionality for temporal positional encoding of pointers + pointer_tpos_dim = num_channels + + # Normalize temporal differences before sine PE calculation + normalized_temporal_diffs = ( + torch.tensor(temporal_offsets, device=device, dtype=torch.float32) / max_temporal_diff + ) + sine_pe = get_1d_sine_pe(normalized_temporal_diffs, dim=pointer_tpos_dim).to(object_pointers.dtype) + projected_sine_pe = self.temporal_positional_encoding_projection_layer(sine_pe) + object_pointers_pos_embed = projected_sine_pe.unsqueeze(1).expand(-1, batch_size, self.mem_dim) + else: + object_pointers_pos_embed = object_pointers.new_zeros( + len(temporal_offsets), batch_size, self.mem_dim, dtype=object_pointers.dtype + ) + + if self.mem_dim < num_channels: + # If memory dimension is smaller, reshape/split pointers and repeat positional encoding + num_splits = num_channels // self.mem_dim + object_pointers = object_pointers.reshape(-1, batch_size, num_splits, self.mem_dim) + object_pointers = object_pointers.permute(0, 2, 1, 3).flatten( + 0, 1 + ) # (SeqLen_ptr*num_splits, Batch, MemDim) + object_pointers_pos_embed = object_pointers_pos_embed.repeat_interleave(num_splits, dim=0) + + return object_pointers, object_pointers_pos_embed + + def _prepare_memory_conditioned_features( + self, + inference_session: Sam2VideoInferenceSession, + frame_idx: int, + obj_idx: int, + is_initial_conditioning_frame: bool, + current_vision_features: list[torch.Tensor], + current_vision_positional_embeddings: list[torch.Tensor], + num_total_frames: int, + track_in_reverse_time: bool = False, + streaming: bool = False, + ) -> torch.Tensor: + """ + Fuse current frame's visual features with memory from previous frames for enhanced object tracking. + + This method conditions the current frame's visual features on temporal memory from previous frames, + enabling consistent object tracking across video sequences. For initial conditioning frames, it uses + no-memory embeddings. For subsequent frames, it retrieves and integrates memory features from both + conditioning frames (user interactions) and non-conditioning frames (tracked results) via cross-attention. + + Args: + inference_session (`Sam2VideoInferenceSession`): + The video inference session object. + frame_idx (`int`): + Index of the current frame being processed. + obj_idx (`int`): + Index of the object being processed. + is_initial_conditioning_frame (`bool`): + Whether this is an initial conditioning frame with user inputs (True) or a subsequent + tracking frame (False). + current_vision_features (`torch.Tensor`): + Highest-level vision features of shape `(seq_len, batch_size, channels)`. + current_vision_positional_embeddings (`torch.Tensor`): + Positional embedding tensors corresponding to the highest-level vision features. + num_total_frames (`int`): + Total number of frames in the video sequence. + track_in_reverse_time (`bool`, *optional*, defaults to `False`): + Whether tracking is performed in reverse temporal order. + streaming (`bool`, *optional*, defaults to `False`): + Whether this is streaming inference mode. + + Returns: + `torch.Tensor`: Memory-conditioned feature tensor of shape `(batch_size, channels, height, width)` + suitable for input to the SAM decoder. + """ + # Get dimensions from the highest-level (lowest-resolution) feature map + batch_size = current_vision_features.size(1) + num_channels = self.hidden_dim + height, width = self.backbone_feature_sizes[-1] + device = current_vision_features.device + + # If memory is disabled (e.g., for single image SAM), return current features directly. + if self.num_maskmem == 0: + # Permute (SeqLen, Batch, Channels) -> (Batch, Channels, SeqLen) then view as (Batch, Channels, Height, Width) + # Assuming SeqLen = Height * Width for the last feature map + current_feature_map = current_vision_features.permute(1, 2, 0).view( + batch_size, num_channels, height, width + ) + return current_feature_map + + # Step 1: Handle initial conditioning frames + if is_initial_conditioning_frame: + # For initial conditioning frames, no prior memory is used directly in this block. + # If configured, directly add a learnable "no memory" embedding. + # current_vision_features has shape (SeqLen, Batch, Channels) + conditioned_feature_map_flat = current_vision_features + self.no_memory_embedding + # Reshape to (Batch, Channels, Height, Width) + conditioned_feature_map = conditioned_feature_map_flat.permute(1, 2, 0).view( + batch_size, num_channels, height, width + ) + return conditioned_feature_map + + # Step 2: Get memory frames and concatenate their features + temporal_positions_and_previous_outputs = self._gather_memory_frame_outputs( + inference_session, obj_idx, frame_idx, track_in_reverse_time + ) + + memories_to_concatenate, memory_positional_embeddings_to_concatenate = self._build_memory_attention_inputs( + temporal_positions_and_previous_outputs, device + ) + + # Step 3: Get and process object pointers + temporal_offsets, pointer_tokens, max_object_pointers_to_use = self._get_object_pointers( + inference_session, obj_idx, frame_idx, num_total_frames, device, track_in_reverse_time, streaming + ) + + num_object_pointer_tokens = 0 + if pointer_tokens: + object_pointers, object_pointers_pos_embed = self._process_object_pointers( + temporal_offsets, pointer_tokens, max_object_pointers_to_use, batch_size, num_channels, device + ) + + if object_pointers is not None: + memories_to_concatenate.append(object_pointers) + memory_positional_embeddings_to_concatenate.append(object_pointers_pos_embed) + num_object_pointer_tokens = object_pointers.shape[0] + + # Step 4: Concatenate all retrieved memories and their positional embeddings + combined_memory = torch.cat(memories_to_concatenate, dim=0).to(dtype=inference_session.dtype) + combined_memory_positional_embeddings = torch.cat(memory_positional_embeddings_to_concatenate, dim=0) + + # Step 5: Forward through the memory attention mechanism + conditioned_feature_map_flat = self.memory_attention( + current_vision_features=current_vision_features, + current_vision_position_embeddings=current_vision_positional_embeddings, + memory=combined_memory, + memory_posision_embeddings=combined_memory_positional_embeddings, # Corrected typo from API + num_object_pointer_tokens=num_object_pointer_tokens, + ) + + # Reshape from (Batch, H*W, Channels) to (Batch, Channels, Height, Width) + conditioned_feature_map = ( + conditioned_feature_map_flat.squeeze(1).permute(0, 2, 1).view(batch_size, num_channels, height, width) + ) + return conditioned_feature_map + + def _use_multimask(self, is_init_cond_frame: bool, point_inputs: dict | None) -> bool: + """Whether to use multimask output in the SAM head.""" + num_pts = 0 if point_inputs is None else point_inputs["point_labels"].size(2) + multimask_output = ( + self.config.multimask_output_in_sam + and (is_init_cond_frame or self.config.multimask_output_for_tracking) + and (self.config.multimask_min_pt_num <= num_pts <= self.config.multimask_max_pt_num) + ) + return multimask_output + + def _run_single_frame_inference( + self, + inference_session: Sam2VideoInferenceSession, + frame_idx: int, + obj_idx: int, + batch_size: int, + is_init_cond_frame: bool, + point_inputs: torch.Tensor | None, + mask_inputs: torch.Tensor | None, + reverse: bool, + prev_sam_mask_logits: torch.Tensor | None = None, + streaming: bool = False, + ) -> dict[str, Any]: + """ + Perform a single tracking step for video object segmentation. + + Args: + inference_session (`Sam2VideoInferenceSession`): + The video inference session object. + frame_idx (`int`): + Index of the current frame. + obj_idx (`int`): + Index of the current object. + batch_size (`int`): + Batch size of the current frame. + is_init_cond_frame (`bool`): + Whether this is an initial conditioning frame with user inputs. + point_inputs (`dict`, *optional*): + Point prompt inputs for the current frame. + mask_inputs (`torch.Tensor`, *optional*): + Mask prompt inputs for the current frame. + reverse (`bool`, *optional*, defaults to `False`): + Whether to track in reverse time order. + prev_sam_mask_logits (`torch.Tensor`, *optional*): + Previously predicted SAM mask logits that can be fed with new clicks. + streaming (`bool`, *optional*, defaults to `False`): + Whether this is streaming inference. + + Returns: + `dict`: Dictionary containing the tracking results for the current frame, including: + - pred_masks: Predicted low-resolution masks. + - object_pointer: Object pointer for memory. + - high_res_masks: High-resolution masks for batched memory encoding. + - object_score_logits: Object score logits (inference only). + """ + # Retrieve correct image features + current_vision_feats, current_vision_pos_embeds = self._prepare_vision_features( + inference_session, frame_idx, batch_size + ) + # point and mask should not appear as input simultaneously on the same frame + if point_inputs is not None and mask_inputs is not None: + raise ValueError( + "point_inputs and mask_inputs should not appear as input simultaneously on the same frame" + ) + # High-resolution feature maps for the SAM head, reshape (HW)BC => BCHW + if len(current_vision_feats) > 1: + high_res_features = [ + x.permute(1, 2, 0).view(x.size(1), x.size(2), *s) + for x, s in zip(current_vision_feats[:-1], self.backbone_feature_sizes[:-1]) + ] + else: + high_res_features = None + if mask_inputs is not None: + # We directly output the mask input (see it as a GT mask) without using a SAM prompt encoder + mask decoder. + pix_feat = current_vision_feats[-1].permute(1, 2, 0) + pix_feat = pix_feat.view(-1, self.hidden_dim, *self.backbone_feature_sizes[-1]) + sam_outputs = self._use_mask_as_output(pix_feat, high_res_features, mask_inputs) + else: + # fused the visual feature with previous memory features in the memory bank + pix_feat = self._prepare_memory_conditioned_features( + inference_session=inference_session, + frame_idx=frame_idx, + obj_idx=obj_idx, + is_initial_conditioning_frame=is_init_cond_frame, + current_vision_features=current_vision_feats[-1], + current_vision_positional_embeddings=current_vision_pos_embeds[-1], + num_total_frames=inference_session.num_frames, + track_in_reverse_time=reverse, + streaming=streaming, + ) + # apply SAM-style segmentation head + # here we might feed previously predicted low-res SAM mask logits into the SAM mask decoder, + # e.g. in demo where such logits come from earlier interaction instead of correction sampling + # (in this case, any `mask_inputs` shouldn't reach here as they are sent to _use_mask_as_output instead) + if prev_sam_mask_logits is not None: + mask_inputs = prev_sam_mask_logits + multimask_output = self._use_multimask(is_init_cond_frame, point_inputs) + sam_outputs = self._single_frame_forward( + pixel_values=None, # Vision features already computed + input_points=point_inputs["point_coords"] if point_inputs is not None else None, + input_labels=point_inputs["point_labels"] if point_inputs is not None else None, + input_masks=mask_inputs, + image_embeddings=high_res_features + [pix_feat], + multimask_output=multimask_output, + ) + + # Memory encoding is now handled in batch by the caller (forward method) + current_out = { + "pred_masks": sam_outputs.pred_masks, + "object_pointer": sam_outputs.object_pointer, + "high_res_masks": sam_outputs.high_res_masks, # Needed for batched memory encoding + } + if not self.training: + current_out["object_score_logits"] = sam_outputs.object_score_logits + + return current_out + + def _encode_new_memory( + self, + current_vision_feats: torch.Tensor, + pred_masks_high_res: torch.Tensor, + object_score_logits: torch.Tensor, + is_mask_from_pts: bool, + ) -> tuple[torch.Tensor, list[torch.Tensor]]: + """Encode the current image and its prediction into a memory feature.""" + batch_size = current_vision_feats.size(1) # batch size on this frame + channels = self.hidden_dim + height, width = self.backbone_feature_sizes[-1] # top-level (lowest-resolution) feature size + + mask_input_size_h, mask_input_size_w = self.prompt_encoder.mask_input_size + mask_mem_size_h = mask_input_size_h * 4 + mask_mem_size_w = mask_input_size_w * 4 + if pred_masks_high_res.shape[2:] != (mask_mem_size_h, mask_mem_size_w): + # downsample the predicted high-res masks into the mask encoder input size + pred_masks_high_res = F.interpolate( + pred_masks_high_res.float(), + size=(mask_mem_size_h, mask_mem_size_w), + align_corners=False, + mode="bilinear", + antialias=True, # use antialias for downsampling + ).to(pred_masks_high_res.dtype) + + # top-level feature, (HW)BC => BCHW + pix_feat = current_vision_feats.permute(1, 2, 0).view(batch_size, channels, height, width) + if is_mask_from_pts and not self.training: + # binarize the mask logits + mask_for_mem = (pred_masks_high_res > 0).to(pred_masks_high_res.dtype) + else: + # apply sigmoid on the raw mask logits to turn them into range (0, 1) + mask_for_mem = torch.sigmoid(pred_masks_high_res) + # apply scale and bias terms to the sigmoid probabilities + mask_for_mem = mask_for_mem * self.config.sigmoid_scale_for_mem_enc + mask_for_mem = mask_for_mem + self.config.sigmoid_bias_for_mem_enc + + maskmem_features, maskmem_pos_enc = self.memory_encoder( + pix_feat, + mask_for_mem, + ) + # add a no-object embedding to the spatial memory to indicate that the frame + # is predicted to be occluded (i.e. no object is appearing in the frame) + if self.occlusion_spatial_embedding_parameter is not None: + is_obj_appearing = (object_score_logits > 0).float() + maskmem_features += (1 - is_obj_appearing[..., None]) * self.occlusion_spatial_embedding_parameter[ + ..., None, None + ].expand(*maskmem_features.shape) + + # convert to bfloat16 to save memory, and for consistency with the original implementation + maskmem_features = maskmem_features.to(torch.bfloat16).flatten(2).permute(2, 0, 1) + maskmem_pos_enc = maskmem_pos_enc.to(pred_masks_high_res.dtype).flatten(2).permute(2, 0, 1) + + return maskmem_features, maskmem_pos_enc + + @torch.inference_mode() + @auto_docstring(custom_intro="Propagate the objects through a streamed video frame.") + def forward( + self, + inference_session: Sam2VideoInferenceSession, + frame_idx: int | None = None, + frame: torch.Tensor | None = None, + reverse: bool = False, + run_mem_encoder: bool = True, + **kwargs, + ) -> Sam2VideoSegmentationOutput: + r""" + inference_session (`Sam2VideoInferenceSession`): + The video inference session object. + frame_idx (`int`, *optional*): + The index of the frame on which to run inference. No need to provide when inferring + on a new streamed frame. + frame (`torch.Tensor`, *optional*): + The frame to process. Provide when streaming. + reverse (`bool`, *optional*, defaults to `False`): + Whether to propagate in reverse. + run_mem_encoder (`bool`, *optional*, defaults to `True`): + Whether to run the memory encoder on predicted masks. The memory encoder is batched across all objects for efficiency. + """ + if frame is not None: + frame_idx = inference_session.add_new_frame(frame, frame_idx) + + if frame is not None and inference_session.get_obj_num() == 0: + raise ValueError("No objects are provided for tracking; please add inputs first.") + + num_objects = inference_session.get_obj_num() + pred_masks_per_obj = [None] * num_objects + object_score_logits_per_obj = [None] * num_objects + + # Collect data for batched memory encoding + objects_needing_memory_encoding = [] + high_res_masks_for_memory = [] + object_score_logits_for_memory = [] + is_mask_from_pts_per_obj = [] + + # Note: We avoid batched inference here because per-object inputs (clicks/masks) + # can differ across objects. + for obj_idx in range(num_objects): + obj_id = inference_session.obj_idx_to_id(obj_idx) + has_new_inputs = obj_id in inference_session.obj_with_new_inputs + has_cond_output = frame_idx in inference_session.output_dict_per_obj[obj_idx]["cond_frame_outputs"] + # If this object has no new inputs and this frame already has a + # conditioning output, reuse the cached masks instead of recomputing. + if (not has_new_inputs) and has_cond_output: + pred_masks = inference_session.get_output(obj_idx, frame_idx, "pred_masks", is_conditioning_frame=True) + object_score_logits = inference_session.get_output( + obj_idx, frame_idx, "object_score_logits", is_conditioning_frame=True + ) + is_init_cond_frame = True + else: + # Defaults when there are no new inputs + is_init_cond_frame = False + point_inputs = None + mask_inputs = None + + if has_new_inputs: + is_init_cond_frame = frame_idx not in inference_session.frames_tracked_per_obj[obj_idx] + if is_init_cond_frame: + reverse = False + point_inputs = inference_session.point_inputs_per_obj[obj_idx].get(frame_idx, None) + mask_inputs = inference_session.mask_inputs_per_obj[obj_idx].get(frame_idx, None) + if point_inputs is not None or mask_inputs is not None: + inference_session.obj_with_new_inputs.remove(obj_id) + + current_out = self._run_single_frame_inference( + inference_session=inference_session, + obj_idx=obj_idx, + frame_idx=frame_idx, + batch_size=1, # run on the slice of a single object + is_init_cond_frame=is_init_cond_frame, + point_inputs=point_inputs, + mask_inputs=mask_inputs, + reverse=reverse, + streaming=frame is not None, + ) + inference_session.store_output( + obj_idx, frame_idx, output_value=current_out, is_conditioning_frame=is_init_cond_frame + ) + pred_masks = current_out["pred_masks"] + object_score_logits = current_out["object_score_logits"] + + # Collect data for batched memory encoding + if run_mem_encoder and self.num_maskmem > 0: + objects_needing_memory_encoding.append(obj_idx) + high_res_masks_for_memory.append(current_out["high_res_masks"]) + object_score_logits_for_memory.append(object_score_logits) + is_mask_from_pts_per_obj.append(point_inputs is not None or mask_inputs is not None) + + pred_masks_per_obj[obj_idx] = pred_masks + object_score_logits_per_obj[obj_idx] = object_score_logits.squeeze(-1) + if not is_init_cond_frame: + # only for tracked frames, not for initial conditioning frames + inference_session.frames_tracked_per_obj[obj_idx][frame_idx] = {"reverse": reverse} + + # Batch encode memories for all objects at once + self._batch_encode_memories( + inference_session=inference_session, + frame_idx=frame_idx, + objects_needing_memory_encoding=objects_needing_memory_encoding, + high_res_masks_for_memory=high_res_masks_for_memory, + object_score_logits_for_memory=object_score_logits_for_memory, + is_mask_from_pts_per_obj=is_mask_from_pts_per_obj, + ) + + # Resize the output mask to the original video resolution (we directly use + # the mask scores on GPU for output to avoid any CPU conversion in between) + if len(pred_masks_per_obj) > 1: + all_pred_masks = torch.cat(pred_masks_per_obj, dim=0) + all_object_score_logits = torch.cat(object_score_logits_per_obj, dim=0) + else: + all_pred_masks = pred_masks_per_obj[0] + all_object_score_logits = object_score_logits_per_obj[0] + + return Sam2VideoSegmentationOutput( + object_ids=inference_session.obj_ids.copy(), + pred_masks=all_pred_masks, + object_score_logits=all_object_score_logits, + frame_idx=frame_idx, + ) + + def _batch_encode_memories( + self, + inference_session: Sam2VideoInferenceSession, + frame_idx: int, + objects_needing_memory_encoding: list[int], + high_res_masks_for_memory: list[torch.Tensor], + object_score_logits_for_memory: list[torch.Tensor], + is_mask_from_pts_per_obj: list[bool], + ): + """ + Batch encode memories for multiple objects at once. + + Args: + inference_session: The video inference session object + frame_idx: Index of the current frame + objects_needing_memory_encoding: List of object indices that need memory encoding + high_res_masks_for_memory: List of high-resolution masks for each object + object_score_logits_for_memory: List of object score logits for each object + is_mask_from_pts_per_obj: List of booleans indicating if mask is from points for each object + """ + if not objects_needing_memory_encoding: + return + + # Get vision features once for all objects + current_vision_feats, _ = self._prepare_vision_features(inference_session, frame_idx, batch_size=1) + + # Stack all high-res masks and object scores + high_res_masks_batched = torch.cat(high_res_masks_for_memory, dim=0) + object_score_logits_batched = torch.cat(object_score_logits_for_memory, dim=0) + + # Expand vision features to match batch size + expanded_vision_feats = current_vision_feats[-1].expand(-1, len(objects_needing_memory_encoding), -1) + + # Encode all memories in one batch call + maskmem_features_batched, maskmem_pos_enc_batched = self._encode_new_memory( + current_vision_feats=expanded_vision_feats, + pred_masks_high_res=high_res_masks_batched, + object_score_logits=object_score_logits_batched, + is_mask_from_pts=any(is_mask_from_pts_per_obj), + ) + + # Split and store encoded memories per object + for i, obj_idx in enumerate(objects_needing_memory_encoding): + # Extract per-object memory from batched result + maskmem_features = maskmem_features_batched[:, i : i + 1] + maskmem_pos_enc = maskmem_pos_enc_batched[:, i : i + 1] + + # Update the stored output with memory features + output_dict = inference_session.output_dict_per_obj[obj_idx] + # Determine if this was a conditioning frame + storage_key = ( + "cond_frame_outputs" if frame_idx in output_dict["cond_frame_outputs"] else "non_cond_frame_outputs" + ) + if frame_idx in output_dict[storage_key]: + output_dict[storage_key][frame_idx]["maskmem_features"] = maskmem_features + output_dict[storage_key][frame_idx]["maskmem_pos_enc"] = maskmem_pos_enc + + @torch.inference_mode() + @auto_docstring( + custom_intro=""" + Propagate the objects through the video frames. Used when initializing an inference session with a whole video. + Yields Sam2VideoSegmentationOutput for each frame. + """ + ) + def propagate_in_video_iterator( + self, + inference_session: Sam2VideoInferenceSession, + start_frame_idx: int | None = None, + max_frame_num_to_track: int | None = None, + reverse: bool = False, + show_progress_bar: bool = False, + ) -> Iterator[Sam2VideoSegmentationOutput]: + r""" + inference_session (`Sam2VideoInferenceSession`): + The video inference session object. + start_frame_idx (`int`, *optional*): + The starting frame index for propagation. + Need to be provided if `forward` hasn't been called on new inputs yet. + If not provided, the starting frame index will be the earliest frame with input points. + max_frame_num_to_track (`int`, *optional*): + The maximum number of frames to track. + reverse (`bool`, *optional*, defaults to `False`): + Whether to propagate in reverse. + show_progress_bar (`bool`, *optional*, defaults to `False`): + Whether to show a progress bar during propagation. + """ + num_frames = inference_session.num_frames + + # set start index, end index, and processing order + if start_frame_idx is None: + # default: start from the earliest frame with input points + frames_with_inputs = [ + frame_idx + for obj_output_dict in inference_session.output_dict_per_obj.values() + for frame_idx in obj_output_dict["cond_frame_outputs"] + ] + if not frames_with_inputs: + raise ValueError( + "Cannot determine the starting frame index; please specify it manually, or run inference on a frame with inputs first." + ) + start_frame_idx = min(frames_with_inputs) + if max_frame_num_to_track is None: + # default: track all the frames in the video + max_frame_num_to_track = num_frames + if reverse: + end_frame_idx = max(start_frame_idx - max_frame_num_to_track, 0) + if start_frame_idx > 0: + processing_order = range(start_frame_idx, end_frame_idx - 1, -1) + else: + processing_order = [] # skip reverse tracking if starting from frame 0 + else: + end_frame_idx = min(start_frame_idx + max_frame_num_to_track, num_frames - 1) + processing_order = range(start_frame_idx, end_frame_idx + 1) + + for frame_idx in tqdm(processing_order, desc="propagate in video", disable=not show_progress_bar): + sam2_video_output = self(inference_session, frame_idx=frame_idx, reverse=reverse) + yield sam2_video_output + + +__all__ = [ + "Sam2VideoModel", + "Sam2VideoInferenceSession", + "Sam2VideoPreTrainedModel", + "Sam2VideoMaskDecoderConfig", + "Sam2VideoPromptEncoderConfig", + "Sam2VideoProcessor", + "Sam2VideoConfig", +] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam2_video/processing_sam2_video.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam2_video/processing_sam2_video.py new file mode 100644 index 0000000000000000000000000000000000000000..416c5c543fe2325e6058dd166c07e1c2b8eb72a7 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam2_video/processing_sam2_video.py @@ -0,0 +1,801 @@ +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# This file was automatically generated from src/transformers/models/sam2_video/modular_sam2_video.py. +# Do NOT edit this file manually as any edits will be overwritten by the generation of +# the file from the modular. If any change should be done, please apply the change to the +# modular_sam2_video.py file directly. One of our CI enforces this. +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# Copyright 2025 The Meta AI Authors and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from copy import deepcopy +from typing import Union + +import numpy as np +import torch + +from ...image_utils import ImageInput +from ...processing_utils import ProcessorMixin +from ...tokenization_utils_base import BatchEncoding +from ...utils import TensorType, auto_docstring +from ...utils.import_utils import requires +from ...video_utils import VideoInput +from .modeling_sam2_video import Sam2VideoInferenceSession + + +@requires(backends=("torch",)) +@auto_docstring +class Sam2VideoProcessor(ProcessorMixin): + def __init__( + self, image_processor, video_processor, target_size: int | None = None, point_pad_value: int = -10, **kwargs + ): + r""" + target_size (`int`, *optional*): + The target size (in pixels) for normalizing input points and bounding boxes. If not provided, defaults + to the image processor's size configuration. All input coordinates (points and boxes) are normalized + to this size before being passed to the model. This ensures consistent coordinate representation + regardless of the original image dimensions. + point_pad_value (`int`, *optional*, defaults to -10): + The value used for padding input points when batching sequences of different lengths. This value is + used to mark padded positions and is preserved during coordinate normalization. + """ + super().__init__(image_processor, video_processor, **kwargs) + self.point_pad_value = point_pad_value + self.target_size = target_size if target_size is not None else self.image_processor.size["height"] + + @auto_docstring + def __call__( + self, + images: ImageInput | None = None, + segmentation_maps: ImageInput | None = None, + input_points: list[list[list[list[float]]]] | torch.Tensor | None = None, + input_labels: list[list[list[int]]] | torch.Tensor | None = None, + input_boxes: list[list[list[float]]] | torch.Tensor | None = None, + original_sizes: list[list[float]] | torch.Tensor | None = None, + return_tensors: str | TensorType | None = None, + **kwargs, + ) -> BatchEncoding: + r""" + segmentation_maps (`ImageInput`, *optional*): + The segmentation maps to process. + input_points (`list[list[list[list[float]]]]`, `torch.Tensor`, *optional*): + The points to add to the frame. + input_labels (`list[list[list[int]]]`, `torch.Tensor`, *optional*): + The labels for the points. + input_boxes (`list[list[list[float]]]`, `torch.Tensor`, *optional*): + The bounding boxes to add to the frame. + original_sizes (`list[list[float]]`, `torch.Tensor`, *optional*): + The original sizes of the images. + + Returns: + A [`BatchEncoding`] with the following fields: + - `pixel_values` (`torch.Tensor`): The processed image(s). + - `original_sizes` (`list[list[float]]`): The original sizes of the images. + - `labels` (`torch.Tensor`): The processed segmentation maps (if provided). + - `input_points` (`torch.Tensor`): The processed points. + - `input_labels` (`torch.Tensor`): The processed labels. + - `input_boxes` (`torch.Tensor`): The processed bounding boxes. + """ + if images is not None: + encoding_image_processor = self.image_processor( + images, + segmentation_maps=segmentation_maps, + return_tensors=return_tensors, + **kwargs, + ) + elif original_sizes is not None: + if isinstance(original_sizes, torch.Tensor): + original_sizes = original_sizes.cpu().tolist() + encoding_image_processor = BatchEncoding({"original_sizes": original_sizes}, tensor_type=return_tensors) + else: + raise ValueError("Either images or original_sizes must be provided") + + # pop arguments that are not used in the forward but used nevertheless + original_sizes = encoding_image_processor["original_sizes"] + # Check original_sizes is of length 1 or len(images) + if images is not None and len(original_sizes) != 1 and len(original_sizes) != len(images): + raise ValueError( + "original_sizes must be of length 1 or len(images). If you are passing a single image, you must pass a single original_size." + ) + + # Process input points, labels, and boxes if provided + if input_points is not None or input_labels is not None or input_boxes is not None: + # Validate and convert inputs to standardized format + processed_points = self._validate_single_input( + input_points, + expected_depth=4, + input_name="points", + expected_format="[image level, object level, point level, point coordinates]", + expected_coord_size=2, + ) + processed_labels = self._validate_single_input( + input_labels, + expected_depth=3, + input_name="labels", + expected_format="[image level, object level, point level]", + ) + processed_boxes = self._validate_single_input( + input_boxes, + expected_depth=3, + input_name="boxes", + expected_format="[image level, box level, box coordinates]", + expected_coord_size=4, + ) + + # Get padding requirements for all inputs + if processed_points is not None: + points_max_dims = self._get_nested_dimensions(processed_points)[:3] + if processed_labels is not None: + labels_max_dims = self._get_nested_dimensions(processed_labels)[:3] + if processed_boxes is not None: + boxes_max_dims = self._get_nested_dimensions(processed_boxes)[:2] + + # Ensure points and labels have consistent dimensions + if processed_points is not None and processed_labels is not None: + if points_max_dims != labels_max_dims: + raise ValueError( + "Input points and labels have inconsistent dimensions. Please ensure they have the same dimensions." + ) + + # Check that boxes don't need padding (model limitation) + if processed_boxes is not None and len(processed_boxes) >= 2: + if any(len(img_boxes) < boxes_max_dims[1] for img_boxes in processed_boxes): + raise ValueError( + "Input boxes have inconsistent dimensions that would require padding, " + "but boxes cannot be padded due to model limitations. " + "Please ensure all images have the same number of boxes." + ) + + # Pad and normalize all inputs to final tensor format + if processed_points is not None: + padded_points = self._pad_nested_list(processed_points, points_max_dims + [2]) + final_points = torch.tensor(padded_points, dtype=torch.float32) + self._normalize_tensor_coordinates(final_points, original_sizes, preserve_padding=True) + encoding_image_processor.update({"input_points": final_points}) + + if processed_labels is not None: + padded_labels = self._pad_nested_list(processed_labels, labels_max_dims) + final_labels = torch.tensor(padded_labels, dtype=torch.int64) + encoding_image_processor.update({"input_labels": final_labels}) + + if processed_boxes is not None: + final_boxes = torch.tensor(processed_boxes, dtype=torch.float32) + self._normalize_tensor_coordinates(final_boxes, original_sizes, is_bounding_box=True) + encoding_image_processor.update({"input_boxes": final_boxes}) + + return encoding_image_processor + + def _normalize_coordinates( + self, target_size: int, coords: "torch.Tensor", original_size, is_bounding_box=False + ) -> "torch.Tensor": + """ + Expects a numpy array of length 2 in the final dimension. Requires the original image size in (H, W) format. + + Args: + target_size (`int`): + The target size of the image. + coords (`torch.Tensor`): + The coordinates to be normalized. + original_size (`tuple`): + The original size of the image. + is_bounding_box (`bool`, *optional*, defaults to `False`): + Whether the coordinates are bounding boxes. + """ + old_h, old_w = original_size + new_h, new_w = target_size, target_size + coords = deepcopy(coords).float() + + if is_bounding_box: + coords = coords.reshape(-1, 2, 2) + coords[..., 0] = coords[..., 0] * (new_w / old_w) + coords[..., 1] = coords[..., 1] * (new_h / old_h) + + if is_bounding_box: + coords = coords.reshape(-1, 4) + + return coords + + def _convert_to_nested_list(self, data, expected_depth, current_depth=0): + """ + Recursively convert various input formats (tensors, numpy arrays, lists) to nested lists. + + Args: + data: Input data in any format + expected_depth: Expected nesting depth + current_depth: Current depth in recursion + + Returns: + Nested list representation of the data + """ + if data is None: + return None + + # Convert tensor/numpy to list if we're at a leaf level or if it's a multi-dimensional array + if isinstance(data, torch.Tensor): # PyTorch tensor + if current_depth == expected_depth - 2 or len(data.shape) <= 2: # At coordinate level or small tensor + return data.numpy().tolist() + else: + return [self._convert_to_nested_list(item, expected_depth, current_depth + 1) for item in data] + elif isinstance(data, np.ndarray): # NumPy array + if current_depth == expected_depth - 2 or len(data.shape) <= 2: # At coordinate level or small array + return data.tolist() + else: + return [self._convert_to_nested_list(item, expected_depth, current_depth + 1) for item in data] + elif isinstance(data, list): + if current_depth == expected_depth: + # We've reached the expected depth, return as is + return data + else: + # Continue recursion + return [self._convert_to_nested_list(item, expected_depth, current_depth + 1) for item in data] + elif isinstance(data, (int, float)): + return data + else: + raise TypeError(f"Unsupported data type: {type(data)}") + + def _get_nested_dimensions(self, nested_list, max_dims=None): + """ + Get the maximum dimensions at each level of nesting. + + Args: + nested_list (`list`): + Nested list structure. + max_dims (`list`, *optional*): + Current maximum dimensions (for recursion). + + Returns: + `list`: A list of maximum dimensions for each nesting level. + """ + if max_dims is None: + max_dims = [] + + if not isinstance(nested_list, list): + return max_dims + + if len(max_dims) == 0: + max_dims.append(len(nested_list)) + else: + max_dims[0] = max(max_dims[0], len(nested_list)) + + if len(nested_list) > 0: + for item in nested_list: + if isinstance(item, list): + sub_dims = self._get_nested_dimensions(item) + # Merge sub_dims into max_dims + for i, dim in enumerate(sub_dims): + if i + 1 >= len(max_dims): + max_dims.append(dim) + else: + max_dims[i + 1] = max(max_dims[i + 1], dim) + + return max_dims + + def _pad_nested_list(self, nested_list, target_dims, current_level=0, pad_value=None): + """ + Recursively pad a nested list to match target dimensions. + + Args: + nested_list (`list`): + Nested list to pad. + target_dims (`list`): + Target dimensions for each level. + current_level (`int`, *optional*, defaults to 0): + Current nesting level. + pad_value (`int`, *optional*): + Value to use for padding. + + Returns: + `list`: The padded nested list. + """ + if pad_value is None: + pad_value = self.point_pad_value + + if current_level >= len(target_dims): + return nested_list + + # Ensure we have a list + if not isinstance(nested_list, list): + nested_list = [nested_list] + + # Pad current level + current_size = len(nested_list) + target_size = target_dims[current_level] + + # Pad with appropriate values + if current_level == len(target_dims) - 1: + # At the coordinate level, pad with pad_value + nested_list.extend([pad_value] * (target_size - current_size)) + else: + # At higher levels, pad with nested structures + if current_size > 0: + # Create appropriately sized template + if current_level < len(target_dims) - 2: + # For non-coordinate levels, create empty nested structure + template_dims = target_dims[current_level + 1 :] + template = self._create_empty_nested_structure(template_dims, pad_value) + else: + # For coordinate level, create list of pad_values + template = [pad_value] * target_dims[current_level + 1] + + nested_list.extend([deepcopy(template) for _ in range(target_size - current_size)]) + else: + # Create from scratch + template_dims = target_dims[current_level + 1 :] + template = self._create_empty_nested_structure(template_dims, pad_value) + nested_list.extend([deepcopy(template) for _ in range(target_size)]) + + # Recursively pad sublists + if current_level < len(target_dims) - 1: + for i in range(len(nested_list)): + if isinstance(nested_list[i], list): + nested_list[i] = self._pad_nested_list(nested_list[i], target_dims, current_level + 1, pad_value) + + return nested_list + + def _create_empty_nested_structure(self, dims, pad_value): + """ + Create an empty nested structure with given dimensions filled with pad_value. + + Args: + dims (`list`): + The dimensions of the nested structure. + pad_value (`int`): + The value to fill the structure with. + """ + if len(dims) == 1: + return [pad_value] * dims[0] + else: + return [self._create_empty_nested_structure(dims[1:], pad_value) for _ in range(dims[0])] + + def _get_nesting_level(self, input_list): + """ + Get the nesting level of a list structure. + + Args: + input_list (`list`): + The list to get the nesting level of. + """ + if isinstance(input_list, list): + if len(input_list) == 0: + return 1 + return 1 + self._get_nesting_level(input_list[0]) + elif isinstance(input_list, (np.ndarray, torch.Tensor)): + # For arrays/tensors, the nesting level is the number of dimensions + return len(input_list.shape) + return 0 + + def _validate_single_input( + self, + data: torch.Tensor | np.ndarray | list, + expected_depth: int, + input_name: str, + expected_format: str, + expected_coord_size: int | None = None, + ) -> list: + """ + Validate a single input by ensuring proper nesting and raising an error if the input is not valid. + + Args: + data (`torch.Tensor`, `np.ndarray`, or `list`): + Input data to process. + expected_depth (`int`): + Expected nesting depth. + input_name (`str`): + Name of the input for error messages. + expected_format (`str`): + The expected format of the input. + expected_coord_size (`int`, *optional*): + Expected coordinate size (2 for points, 4 for boxes, None for labels). + . + """ + if data is None: + return None + + # Handle tensors and numpy arrays first + if isinstance(data, (torch.Tensor, np.ndarray)): + # For tensors/arrays, we can directly check the number of dimensions + if data.ndim != expected_depth: + raise ValueError( + f"Input {input_name} must be a tensor/array with {expected_depth} dimensions. The expected nesting format is {expected_format}. Got {data.ndim} dimensions." + ) + elif expected_coord_size is not None: + if data.shape[-1] != expected_coord_size: + raise ValueError( + f"Input {input_name} must be a tensor/array with {expected_coord_size} as the last dimension, got {data.shape[-1]}." + ) + return self._convert_to_nested_list(data, expected_depth) + + # Handle nested lists + if isinstance(data, list): + current_depth = self._get_nesting_level(data) + if current_depth != expected_depth: + raise ValueError( + f"Input {input_name} must be a nested list with {expected_depth} levels. The expected nesting format is {expected_format}. Got {current_depth} levels." + ) + return self._convert_to_nested_list(data, expected_depth) + + def _normalize_tensor_coordinates(self, tensor, original_sizes, is_bounding_box=False, preserve_padding=False): + """ + Helper method to normalize coordinates in a tensor across multiple images. + + Args: + tensor (`torch.Tensor`): + Input tensor with coordinates. + original_sizes (`list`): + Original image sizes. + is_bounding_box (`bool`, *optional*, defaults to `False`): + Whether coordinates are bounding boxes. + preserve_padding (`bool`, *optional*, defaults to `False`): + Whether to preserve padding values (for points). + """ + if preserve_padding: + # For points: avoid normalizing pad values + mask = tensor != self.point_pad_value + coord_mask = mask.all(dim=-1, keepdim=True) + + for img_idx in range(len(original_sizes)): + if img_idx < tensor.shape[0]: + original_size = original_sizes[img_idx] if img_idx < len(original_sizes) else original_sizes[0] + normalized_coords = self._normalize_coordinates( + self.target_size, tensor[img_idx], original_size, is_bounding_box=is_bounding_box + ) + + if preserve_padding: + # Only update non-padded values + img_mask = coord_mask[img_idx] + tensor[img_idx] = torch.where( + img_mask.expand_as(tensor[img_idx]), normalized_coords, tensor[img_idx] + ) + else: + tensor[img_idx] = normalized_coords + + def post_process_masks( + self, + masks, + original_sizes, + mask_threshold=0.0, + binarize=True, + max_hole_area=0.0, + max_sprinkle_area=0.0, + apply_non_overlapping_constraints=False, + **kwargs, + ): + """ + Remove padding and upscale masks to the original image size. + + Args: + masks (`Union[List[torch.Tensor], List[np.ndarray]]`): + Batched masks from the mask_decoder in (batch_size, num_channels, height, width) format. + original_sizes (`Union[torch.Tensor, List[Tuple[int,int]]]`): + The original sizes of each image before it was resized to the model's expected input shape, in (height, + width) format. + mask_threshold (`float`, *optional*, defaults to 0.0): + Threshold for binarization and post-processing operations. + binarize (`bool`, *optional*, defaults to `True`): + Whether to binarize the masks. + max_hole_area (`float`, *optional*, defaults to 0.0): + The maximum area of a hole to fill. + max_sprinkle_area (`float`, *optional*, defaults to 0.0): + The maximum area of a sprinkle to fill. + apply_non_overlapping_constraints (`bool`, *optional*, defaults to `False`): + Whether to apply non-overlapping constraints to the masks. + + Returns: + (`torch.Tensor`): Batched masks in batch_size, num_channels, height, width) format, where (height, width) + is given by original_size. + """ + return self.image_processor.post_process_masks( + masks, + original_sizes, + mask_threshold, + binarize, + max_hole_area, + max_sprinkle_area, + apply_non_overlapping_constraints, + **kwargs, + ) + + @property + def model_input_names(self): + image_processor_input_names = self.image_processor.model_input_names + return list(image_processor_input_names + ["original_sizes"]) + + def init_video_session( + self, + video: VideoInput | None = None, + inference_device: Union[str, "torch.device"] = "cpu", + inference_state_device: Union[str, "torch.device"] | None = None, + processing_device: Union[str, "torch.device"] | None = None, + video_storage_device: Union[str, "torch.device"] | None = None, + max_vision_features_cache_size: int = 1, + dtype: torch.dtype = torch.float32, + ): + """ + Initializes a video session for inference. + If a video is provided (async inference), the video will be processed and stored on the `video_storage_device`. + + Args: + video (`VideoInput`, *optional*): + The video to process. No need to provide when streaming. + inference_device (`str` or `torch.device`, *optional*, defaults to "cpu"): + The device to use for inference. + inference_state_device (`str` or `torch.device`, *optional*): + The device to store the inference state on. + processing_device (`str` or `torch.device`, *optional*): + The device to use for video processing. + video_storage_device (`str` or `torch.device`, *optional*): + The device to store the processed video frames on. + max_vision_features_cache_size (`int`, *optional*, defaults to 1): + The maximum number of vision features to cache. + dtype (`torch.dtype`, *optional*, defaults to `torch.float32`): + The torch dtype to use for the whole session. + """ + video_storage_device = video_storage_device if video_storage_device is not None else inference_device + inference_state_device = inference_state_device if inference_state_device is not None else inference_device + processing_device = processing_device if processing_device is not None else inference_device + pixel_values_video = None + video_height = None + video_width = None + if video is not None: + processed_video = self.video_processor(videos=video, device=processing_device, return_tensors="pt") + pixel_values_video = processed_video.pixel_values_videos[0] + video_height = processed_video.original_sizes[0][0] + video_width = processed_video.original_sizes[0][1] + inference_session = Sam2VideoInferenceSession( + video=pixel_values_video, + video_height=video_height, + video_width=video_width, + inference_device=inference_device, + video_storage_device=video_storage_device, + inference_state_device=inference_state_device, + dtype=dtype, + max_vision_features_cache_size=max_vision_features_cache_size, + ) + return inference_session + + def add_inputs_to_inference_session( + self, + inference_session: Sam2VideoInferenceSession, + frame_idx: int, + obj_ids: list[int] | int, + input_points: list[list[list[list[float]]]] | torch.Tensor | None = None, + input_labels: list[list[list[int]]] | torch.Tensor | None = None, + input_boxes: list[list[list[float]]] | torch.Tensor | None = None, + input_masks: np.ndarray | torch.Tensor | list[np.ndarray] | list[torch.Tensor] | None = None, + original_size: tuple[int, int] | None = None, + clear_old_inputs: bool = True, + ) -> Sam2VideoInferenceSession: + """ + Process new points, boxes, or masks for a video frame and add them to the inference session. + + Args: + inference_session (`Sam2VideoInferenceSession`): + The inference session for the video. + frame_idx (`int`): + The index of the frame to process. + obj_ids (`list[int]` or `int`): + The object ID(s) to associate with the points or box. + These can be any integers and can be reused later on to specify an object. + input_points (`list[list[list[list[float]]]]`, `torch.Tensor`, *optional*): + The points to add to the frame. + input_labels (`list[list[list[int]]]`, `torch.Tensor`, *optional*): + The labels for the points. + input_boxes (`list[list[list[float]]]`, `torch.Tensor`, *optional*): + The bounding boxes to add to the frame. + input_masks (`np.ndarray`, `torch.Tensor`, `list[np.ndarray]`, or `list[torch.Tensor]`, *optional*): + The mask(s) to add to the frame. + original_size (`tuple[int, int]`, *optional*): + The original size of the video. Provide when streaming. + clear_old_inputs (`bool`, *optional*, defaults to `True`): + Whether to clear old inputs for the object. + """ + + if isinstance(obj_ids, int): + obj_ids = [obj_ids] + + # Validate inputs + if (input_points is not None) != (input_labels is not None): + raise ValueError("points and labels must be provided together") + if input_points is None and input_boxes is None and input_masks is None: + raise ValueError("at least one of points, boxes, or masks must be provided as input") + if input_masks is not None and (input_points is not None or input_boxes is not None): + raise ValueError("masks cannot be provided together with points or boxes") + + if input_masks is not None: + return self.process_new_mask_for_video_frame(inference_session, frame_idx, obj_ids, input_masks) + else: + return self.process_new_points_or_boxes_for_video_frame( + inference_session, + frame_idx, + obj_ids, + input_points, + input_labels, + input_boxes, + original_size, + clear_old_inputs, + ) + + def process_new_points_or_boxes_for_video_frame( + self, + inference_session: Sam2VideoInferenceSession, + frame_idx: int, + obj_ids: list[int], + input_points: list[list[list[list[float]]]] | torch.Tensor | None = None, + input_labels: list[list[list[int]]] | torch.Tensor | None = None, + input_boxes: list[list[list[float]]] | torch.Tensor | None = None, + original_size: tuple[int, int] | None = None, + clear_old_inputs: bool = True, + ) -> Sam2VideoInferenceSession: + """ + Process new points or boxes for a video frame and add them to the inference session. + + Args: + inference_session (`Sam2VideoInferenceSession`): + The inference session for the video. + frame_idx (`int`): + The index of the frame to process. + obj_ids (`list[int]`): + The object ID(s) to associate with the points or box. + These can be any integers and can be reused later on to specify an object. + input_points (`list[list[list[list[float]]]]`, `torch.Tensor`, *optional*): + The points to add to the frame. + input_labels (`list[list[list[int]]]`, `torch.Tensor`, *optional*): + The labels for the points. + input_boxes (`list[list[list[float]]]`, `torch.Tensor`, *optional*): + The bounding boxes to add to the frame. + original_size (`tuple[int, int]`, *optional*): + The original size of the video. Provide when streaming. + clear_old_inputs (`bool`, *optional*, defaults to `True`): + Whether to clear old inputs for the object. + """ + if original_size is not None: + inference_session.video_height = original_size[0] + inference_session.video_width = original_size[1] + elif inference_session.video_height is None or inference_session.video_width is None: + raise ValueError("original_size must be provided when adding points or boxes on a first streamed frame") + + original_sizes = [[inference_session.video_height, inference_session.video_width]] + + encoded_inputs = self( + input_points=input_points, + input_labels=input_labels, + input_boxes=input_boxes, + original_sizes=original_sizes, + return_tensors="pt", + ) + input_points = encoded_inputs.get("input_points", None) + input_labels = encoded_inputs.get("input_labels", None) + input_boxes = encoded_inputs.get("input_boxes", None) + + if input_points is not None: + if input_points.shape[1] != len(obj_ids): + raise ValueError( + f"Number of object ids ({len(obj_ids)}) does not match number of points ({input_points.shape[1]})" + ) + else: + input_points = torch.zeros(1, len(obj_ids), 0, 2, dtype=torch.float32) + if input_labels is not None: + if input_labels.shape[1] != len(obj_ids): + raise ValueError( + f"Number of object ids ({len(obj_ids)}) does not match number of labels ({input_labels.shape[1]})" + ) + else: + input_labels = torch.zeros(1, len(obj_ids), 0, dtype=torch.int32) + if input_boxes is not None: + if input_boxes.shape[1] != len(obj_ids): + raise ValueError( + f"Number of object ids ({len(obj_ids)}) does not match number of boxes ({input_boxes.shape[1]})" + ) + + if input_boxes is not None: + if not clear_old_inputs: + raise ValueError( + "cannot add box without clearing old points, since " + "box prompt must be provided before any point prompt " + "(please use clear_old_points=True instead)" + ) + box_coords = input_boxes.reshape(1, -1, 2, 2) + box_labels = torch.tensor([2, 3], dtype=torch.int32).repeat(1, box_coords.shape[1], 1) + input_points = torch.cat([box_coords, input_points], dim=2) + input_labels = torch.cat([box_labels, input_labels], dim=2) + + for obj_id, idx in zip(obj_ids, range(len(obj_ids))): + obj_idx = inference_session.obj_id_to_idx(obj_id) + input_points_for_obj = input_points[:, idx, :, :].unsqueeze(1) + input_labels_for_obj = input_labels[:, idx, :].unsqueeze(1) + # Handle existing points + if not clear_old_inputs: + existing_points = inference_session.point_inputs_per_obj[obj_idx].get(frame_idx, None) + if existing_points is not None: + # Concatenate with existing points + input_points_for_obj = torch.cat( + [existing_points["point_coords"].to(input_points_for_obj.device), input_points_for_obj], dim=2 + ) + input_labels_for_obj = torch.cat( + [existing_points["point_labels"].to(input_labels_for_obj.device), input_labels_for_obj], dim=2 + ) + point_inputs = { + "point_coords": input_points_for_obj, + "point_labels": input_labels_for_obj, + } + + inference_session.add_point_inputs(obj_idx, frame_idx, point_inputs) + inference_session.remove_mask_inputs(obj_idx, frame_idx) # Clear any mask inputs + + inference_session.obj_with_new_inputs = obj_ids + + def process_new_mask_for_video_frame( + self, + inference_session: Sam2VideoInferenceSession, + frame_idx: int, + obj_ids: list[int], + input_masks: np.ndarray | torch.Tensor | list[np.ndarray] | list[torch.Tensor], + ): + """ + Add new mask to a frame and add them to the inference session. + + Args: + inference_session (`Sam2VideoInferenceSession`): + The inference session for the video. + frame_idx (`int`): + The index of the frame to process. + obj_ids (`list[int]`): + The object ID(s) to associate with the mask. + These can be any integers and can be reused later on to specify an object. + input_masks (`np.ndarray`, `torch.Tensor`, `list[np.ndarray]`, or `list[torch.Tensor]`): + The mask(s) to add to the frame. + """ + if not isinstance(input_masks, list): + input_masks = [input_masks] + if len(input_masks) != len(obj_ids): + raise ValueError( + f"Number of object ids ({len(obj_ids)}) does not match number of masks ({len(input_masks)})" + ) + + for obj_id, mask in zip(obj_ids, input_masks): + obj_idx = inference_session.obj_id_to_idx(obj_id) + + device = inference_session.inference_device + + # Process mask + if not isinstance(mask, torch.Tensor): + mask = torch.tensor(mask, dtype=torch.bool) + nb_dim = mask.dim() + if nb_dim > 4 or nb_dim < 2: + raise ValueError(f"Mask has an unsupported number of dimensions: {nb_dim}") + for i in range(4 - nb_dim): + mask = mask.unsqueeze(0) + + mask_H, mask_W = mask.shape[-2:] + mask_inputs_orig = mask.to(device) + mask_inputs_orig = mask_inputs_orig.float().to(device) + + # Resize mask if needed + if mask_H != self.target_size or mask_W != self.target_size: + mask_inputs = torch.nn.functional.interpolate( + mask_inputs_orig, + size=(self.target_size, self.target_size), + align_corners=False, + mode="bilinear", + antialias=True, + ) + mask_inputs = (mask_inputs >= 0.5).float() + else: + mask_inputs = mask_inputs_orig + + inference_session.add_mask_inputs(obj_idx, frame_idx, mask_inputs) + inference_session.remove_point_inputs(obj_idx, frame_idx) # Clear any point inputs + + inference_session.obj_with_new_inputs = obj_ids + + +__all__ = ["Sam2VideoProcessor"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam2_video/video_processing_sam2_video.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam2_video/video_processing_sam2_video.py new file mode 100644 index 0000000000000000000000000000000000000000..a1dad3a0f4df1dcba48bc8caf1d128a6f0a603f2 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam2_video/video_processing_sam2_video.py @@ -0,0 +1,104 @@ +# Copyright 2025 The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""Fast Image processor class for SAM2.""" + +import numpy as np +import torch +import torch.nn.functional as F + +from ...image_processing_utils import BatchFeature +from ...image_utils import IMAGENET_DEFAULT_MEAN, IMAGENET_DEFAULT_STD, PILImageResampling, SizeDict +from ...utils import TensorType +from ...video_processing_utils import BaseVideoProcessor + + +class Sam2VideoVideoProcessor(BaseVideoProcessor): + resample = PILImageResampling.BILINEAR + image_mean = IMAGENET_DEFAULT_MEAN + image_std = IMAGENET_DEFAULT_STD + size = {"height": 1024, "width": 1024} + do_resize = True + do_rescale = True + do_normalize = True + do_convert_rgb = True + model_input_names = ["pixel_values"] + + def _preprocess( + self, + videos: list["torch.Tensor"], + size: SizeDict, + return_tensors: str | TensorType | None, + **kwargs, + ) -> BatchFeature: + original_sizes = [video.shape[-2:] for video in videos] + reshaped_input_sizes = [(size.height, size.width) for _ in range(len(videos))] + batch_feature = super()._preprocess(videos, size=size, return_tensors=return_tensors, **kwargs) + batch_feature = BatchFeature( + data={ + "original_sizes": original_sizes, + "reshaped_input_sizes": reshaped_input_sizes, + **batch_feature.data, + }, + tensor_type=return_tensors, + ) + return batch_feature + + def post_process_masks( + self, masks, original_sizes, reshaped_input_sizes, mask_threshold=0.0, binarize=True, pad_size=None + ): + """ + Remove padding and upscale masks to the original image size. + + Args: + masks (`Union[List[torch.Tensor], List[np.ndarray]]`): + Batched masks from the mask_decoder in (batch_size, num_channels, height, width) format. + original_sizes (`Union[torch.Tensor, List[Tuple[int,int]]]`): + The original sizes of each image before it was resized to the model's expected input shape, in (height, + width) format. + reshaped_input_sizes (`Union[torch.Tensor, List[Tuple[int,int]]]`): + The size of each image as it is fed to the model, in (height, width) format. Used to remove padding. + mask_threshold (`float`, *optional*, defaults to 0.0): + The threshold to use for binarizing the masks. + binarize (`bool`, *optional*, defaults to `True`): + Whether to binarize the masks. + pad_size (`int`, *optional*, defaults to `self.pad_size`): + The target size the images were padded to before being passed to the model. If None, the target size is + assumed to be the processor's `pad_size`. + Returns: + (`torch.Tensor`): Batched masks in batch_size, num_channels, height, width) format, where (height, width) + is given by original_size. + """ + pad_size = self.size if pad_size is None else pad_size + target_image_size = (pad_size["height"], pad_size["width"]) + if isinstance(original_sizes, (torch.Tensor, np.ndarray)): + original_sizes = original_sizes.tolist() + if isinstance(reshaped_input_sizes, (torch.Tensor, np.ndarray)): + reshaped_input_sizes = reshaped_input_sizes.tolist() + output_masks = [] + for i, original_size in enumerate(original_sizes): + if isinstance(masks[i], np.ndarray): + masks[i] = torch.from_numpy(masks[i]) + elif not isinstance(masks[i], torch.Tensor): + raise TypeError("Input masks should be a list of `torch.tensors` or a list of `np.ndarray`") + interpolated_mask = F.interpolate(masks[i], target_image_size, mode="bilinear", align_corners=False) + interpolated_mask = interpolated_mask[..., : reshaped_input_sizes[i][0], : reshaped_input_sizes[i][1]] + interpolated_mask = F.interpolate(interpolated_mask, original_size, mode="bilinear", align_corners=False) + if binarize: + interpolated_mask = interpolated_mask > mask_threshold + output_masks.append(interpolated_mask) + + return output_masks + + +__all__ = ["Sam2VideoVideoProcessor"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam3/__init__.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam3/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..fda7eeef4fe5b0f4835fd480dfee6c4ea6614d1f --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam3/__init__.py @@ -0,0 +1,28 @@ +# Copyright 2025 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from typing import TYPE_CHECKING + +from ...utils import _LazyModule +from ...utils.import_utils import define_import_structure + + +if TYPE_CHECKING: + from .configuration_sam3 import * + from .modeling_sam3 import * + from .processing_sam3 import * +else: + import sys + + _file = globals()["__file__"] + sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__) diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam3/configuration_sam3.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam3/configuration_sam3.py new file mode 100644 index 0000000000000000000000000000000000000000..8ba86c3eb61b92733e6638a4eb62bd1ca47ba6be --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam3/configuration_sam3.py @@ -0,0 +1,545 @@ +# Copyright 2025 Meta AI and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""SAM3 model configuration""" + +from transformers import CLIPTextConfig + +from ...configuration_utils import PreTrainedConfig +from ..auto import CONFIG_MAPPING, AutoConfig + + +class Sam3ViTConfig(PreTrainedConfig): + r""" + Configuration class for SAM3 Vision Encoder (ViT backbone). + + Instantiating a configuration defaults will yield a similar configuration to that of SAM 3 + [facebook/sam3](https://huggingface.co/facebook/sam3) architecture. + + Args: + hidden_size (`int`, *optional*, defaults to 1024): + Dimensionality of the encoder layers. + intermediate_size (`int`, *optional*, defaults to 4736): + Dimensionality of the feedforward (MLP) layers. + num_hidden_layers (`int`, *optional*, defaults to 32): + Number of hidden layers in the Transformer encoder. + num_attention_heads (`int`, *optional*, defaults to 16): + Number of attention heads for each attention layer. + num_channels (`int`, *optional*, defaults to 3): + Number of input image channels. + image_size (`int`, *optional*, defaults to 1008): + Expected input image size. + patch_size (`int`, *optional*, defaults to 14): + Size of image patches. + hidden_act (`str`, *optional*, defaults to `"gelu"`): + The non-linear activation function. + layer_norm_eps (`float`, *optional*, defaults to 1e-06): + The epsilon used by layer normalization layers. + attention_dropout (`float`, *optional*, defaults to 0.0): + The dropout ratio for attention probabilities. + rope_theta (`float`, *optional*, defaults to 10000.0): + Base frequency for RoPE. + window_size (`int`, *optional*, defaults to 24): + Window size for windowed attention. + global_attn_indexes (`list[int]`, *optional*, defaults to `[7, 15, 23, 31]`): + Indexes of layers with global attention. + layer_scale_init_value (`float`, *optional*): + Initial value for layer scale. None means no layer scale. + pretrain_image_size (`int`, *optional*, defaults to 336): + Pretrained model image size for position embedding initialization. + hidden_dropout (`float`, *optional*, defaults to 0.0): + Dropout probability for hidden states. + initializer_range (`float`, *optional*, defaults to 0.02): + The standard deviation of the truncated_normal_initializer for initializing weight matrices. + """ + + base_config_key = "backbone_config" + model_type = "sam3_vit_model" + + def __init__( + self, + hidden_size=1024, + intermediate_size=4736, + num_hidden_layers=32, + num_attention_heads=16, + num_channels=3, + image_size=1008, + patch_size=14, + hidden_act="gelu", + layer_norm_eps=1e-6, + attention_dropout=0.0, + rope_theta=10000.0, + window_size=24, + global_attn_indexes=None, + layer_scale_init_value=None, + pretrain_image_size=336, + hidden_dropout=0.0, + initializer_range=0.02, + **kwargs, + ): + super().__init__(**kwargs) + if global_attn_indexes is None: + global_attn_indexes = [7, 15, 23, 31] + + self.hidden_size = hidden_size + self.intermediate_size = intermediate_size + self.num_hidden_layers = num_hidden_layers + self.num_attention_heads = num_attention_heads + self.num_channels = num_channels + self.image_size = image_size + self.patch_size = patch_size + self.hidden_act = hidden_act + self.layer_norm_eps = layer_norm_eps + self.attention_dropout = attention_dropout + self.rope_theta = rope_theta + self.window_size = window_size + self.global_attn_indexes = global_attn_indexes + self.layer_scale_init_value = layer_scale_init_value + self.pretrain_image_size = pretrain_image_size + self.hidden_dropout = hidden_dropout + self.initializer_range = initializer_range + + +class Sam3VisionConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`Sam3VisionModel`]. It is used to instantiate a SAM + vision encoder according to the specified arguments, defining the model architecture. Instantiating a configuration + defaults will yield a similar configuration to that of SAM 3 + [facebook/sam3](https://huggingface.co/facebook/sam3) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + backbone_config (`Union[dict, "PreTrainedConfig"]`, *optional*, defaults to `Sam3ViTConfig()`): + Configuration for the vision backbone. This is used to instantiate the backbone using + `AutoModel.from_config`. + fpn_hidden_size (`int`, *optional*, defaults to 256): + The hidden dimension of the FPN. + backbone_feature_sizes (`List[List[int]]`, *optional*, defaults to `[[288, 288], [144, 144], [72, 72]]`): + The spatial sizes (height, width) of the feature maps from the backbone at different scales. + scale_factors (`list[float]`, *optional*, defaults to `[4.0, 2.0, 1.0, 0.5]`): + Scale factors for FPN multi-scale features. List of scaling factors for each FPN level. + hidden_act (`str`, *optional*, defaults to `"gelu"`): + The non-linear activation function in the neck. + layer_norm_eps (`float`, *optional*, defaults to 1e-06): + The epsilon for the layer normalization. + initializer_range (`float`, *optional*, defaults to 0.02): + The standard deviation of the truncated_normal_initializer for initializing all weight matrices. + + """ + + base_config_key = "vision_config" + model_type = "sam3_vision_model" + sub_configs = { + "backbone_config": AutoConfig, + } + + def __init__( + self, + backbone_config=None, + fpn_hidden_size=256, + backbone_feature_sizes=None, + scale_factors=None, + hidden_act="gelu", + layer_norm_eps=1e-6, + initializer_range=0.02, + **kwargs, + ): + scale_factors = [4.0, 2.0, 1.0, 0.5] if scale_factors is None else scale_factors + if backbone_feature_sizes is None: + backbone_feature_sizes = [[288, 288], [144, 144], [72, 72]] + + if isinstance(backbone_config, dict): + backbone_config["model_type"] = backbone_config.get("model_type", "sam3_vit_model") + backbone_config = CONFIG_MAPPING[backbone_config["model_type"]](**backbone_config) + elif backbone_config is None: + backbone_config = CONFIG_MAPPING["sam3_vit_model"]() + + self.backbone_config = backbone_config + + # Neck + self.fpn_hidden_size = fpn_hidden_size + self.scale_factors = scale_factors + self.backbone_feature_sizes = backbone_feature_sizes + + self.hidden_act = hidden_act + self.layer_norm_eps = layer_norm_eps + self.initializer_range = initializer_range + super().__init__(**kwargs) + + @property + def image_size(self): + """Image size for the vision encoder.""" + return self.backbone_config.image_size + + @image_size.setter + def image_size(self, value): + """Set the image size and propagate to backbone.""" + self.backbone_config.image_size = value + + +class Sam3GeometryEncoderConfig(PreTrainedConfig): + r""" + Configuration class for SAM3 Geometry Encoder. + + Args: + hidden_size (`int`, *optional*, defaults to 256): + Dimensionality of the encoder layers. + num_layers (`int`, *optional*, defaults to 3): + Number of transformer encoder layers for processing geometry prompts. + num_attention_heads (`int`, *optional*, defaults to 8): + Number of attention heads in the geometry encoder. + intermediate_size (`int`, *optional*, defaults to 2048): + Dimensionality of the feedforward layers. + dropout (`float`, *optional*, defaults to 0.1): + Dropout probability. + hidden_act (`str`, *optional*, defaults to `"relu"`): + Activation function in FFN. + hidden_dropout (`float`, *optional*, defaults to 0.0): + Dropout probability for hidden states. + layer_norm_eps (`float`, *optional*, defaults to 1e-06): + Epsilon for layer normalization. + roi_size (`int`, *optional*, defaults to 7): + ROI size for box pooling operations. + initializer_range (`float`, *optional*, defaults to 0.02): + The standard deviation of the truncated_normal_initializer for initializing weight matrices. + """ + + model_type = "sam3_geometry_encoder" + + def __init__( + self, + hidden_size=256, + num_layers=3, + num_attention_heads=8, + intermediate_size=2048, + dropout=0.1, + hidden_act="relu", + hidden_dropout=0.0, + layer_norm_eps=1e-6, + roi_size=7, + initializer_range=0.02, + **kwargs, + ): + super().__init__(**kwargs) + self.hidden_size = hidden_size + self.num_layers = num_layers + self.num_attention_heads = num_attention_heads + self.intermediate_size = intermediate_size + self.dropout = dropout + self.hidden_act = hidden_act + self.hidden_dropout = hidden_dropout + self.layer_norm_eps = layer_norm_eps + self.roi_size = roi_size + self.initializer_range = initializer_range + + +class Sam3DETREncoderConfig(PreTrainedConfig): + r""" + Configuration class for SAM3 DETR Encoder (vision-text fusion encoder). + + Args: + hidden_size (`int`, *optional*, defaults to 256): + Dimensionality of the encoder layers. + num_layers (`int`, *optional*, defaults to 6): + Number of encoder layers. + num_attention_heads (`int`, *optional*, defaults to 8): + Number of attention heads. + intermediate_size (`int`, *optional*, defaults to 2048): + Dimensionality of the feedforward layers. + dropout (`float`, *optional*, defaults to 0.1): + Dropout probability. + hidden_act (`str`, *optional*, defaults to `"relu"`): + Activation function in FFN. + hidden_dropout (`float`, *optional*, defaults to 0.0): + Dropout probability for hidden states. + layer_norm_eps (`float`, *optional*, defaults to 1e-06): + Epsilon for layer normalization. + initializer_range (`float`, *optional*, defaults to 0.02): + The standard deviation of the truncated_normal_initializer for initializing weight matrices. + """ + + model_type = "sam3_detr_encoder" + + def __init__( + self, + hidden_size=256, + num_layers=6, + num_attention_heads=8, + intermediate_size=2048, + dropout=0.1, + hidden_act="relu", + hidden_dropout=0.0, + layer_norm_eps=1e-6, + initializer_range=0.02, + **kwargs, + ): + super().__init__(**kwargs) + self.hidden_size = hidden_size + self.num_layers = num_layers + self.num_attention_heads = num_attention_heads + self.intermediate_size = intermediate_size + self.dropout = dropout + self.hidden_act = hidden_act + self.hidden_dropout = hidden_dropout + self.layer_norm_eps = layer_norm_eps + self.initializer_range = initializer_range + + +class Sam3DETRDecoderConfig(PreTrainedConfig): + r""" + Configuration class for SAM3 DETR Decoder (object query decoder). + + Args: + hidden_size (`int`, *optional*, defaults to 256): + Dimensionality of the decoder layers. + num_layers (`int`, *optional*, defaults to 6): + Number of decoder layers. + num_queries (`int`, *optional*, defaults to 200): + Number of object queries. + num_attention_heads (`int`, *optional*, defaults to 8): + Number of attention heads. + intermediate_size (`int`, *optional*, defaults to 2048): + Dimensionality of the feedforward layers. + dropout (`float`, *optional*, defaults to 0.1): + Dropout probability. + hidden_act (`str`, *optional*, defaults to `"relu"`): + Activation function in FFN. + hidden_dropout (`float`, *optional*, defaults to 0.0): + Dropout probability for hidden states. + layer_norm_eps (`float`, *optional*, defaults to 1e-06): + Epsilon for layer normalization. + initializer_range (`float`, *optional*, defaults to 0.02): + The standard deviation of the truncated_normal_initializer for initializing weight matrices. + """ + + model_type = "sam3_detr_decoder" + + def __init__( + self, + hidden_size=256, + num_layers=6, + num_queries=200, + num_attention_heads=8, + intermediate_size=2048, + dropout=0.1, + hidden_act="relu", + hidden_dropout=0.0, + layer_norm_eps=1e-6, + initializer_range=0.02, + **kwargs, + ): + super().__init__(**kwargs) + self.hidden_size = hidden_size + self.num_layers = num_layers + self.num_queries = num_queries + self.num_attention_heads = num_attention_heads + self.intermediate_size = intermediate_size + self.dropout = dropout + self.hidden_act = hidden_act + self.hidden_dropout = hidden_dropout + self.layer_norm_eps = layer_norm_eps + self.initializer_range = initializer_range + + +class Sam3MaskDecoderConfig(PreTrainedConfig): + r""" + Configuration class for SAM3 Mask Decoder (pixel-level mask prediction). + + Args: + hidden_size (`int`, *optional*, defaults to 256): + Dimensionality of the mask decoder. + num_upsampling_stages (`int`, *optional*, defaults to 3): + Number of upsampling stages in the pixel decoder (FPN). + layer_norm_eps (`float`, *optional*, defaults to 1e-06): + Epsilon for layer normalization. + dropout (`float`, *optional*, defaults to 0.0): + Dropout probability for prompt cross-attention. + num_attention_heads (`int`, *optional*, defaults to 8): + Number of attention heads for prompt cross-attention. + initializer_range (`float`, *optional*, defaults to 0.02): + The standard deviation of the truncated_normal_initializer for initializing weight matrices. + """ + + model_type = "sam3_mask_decoder" + + def __init__( + self, + hidden_size=256, + num_upsampling_stages=3, + layer_norm_eps=1e-6, + dropout=0.0, + num_attention_heads=8, + initializer_range=0.02, + **kwargs, + ): + super().__init__(**kwargs) + self.hidden_size = hidden_size + self.num_upsampling_stages = num_upsampling_stages + self.layer_norm_eps = layer_norm_eps + self.dropout = dropout + self.num_attention_heads = num_attention_heads + self.initializer_range = initializer_range + + +class Sam3Config(PreTrainedConfig): + r""" + Configuration class to store the configuration of a [`Sam3Model`]. + + Instantiating a configuration defaults will yield a similar configuration to that of SAM 3 + [facebook/sam3](https://huggingface.co/facebook/sam3) architecture. + + This is the main configuration class that combines all sub-configurations for the SAM3 model. + + + + SAM3 checkpoints with `model_type="sam3_video"` are compatible with `Sam3Model` since the video variant weights + are a superset of the image-only model weights. You may see a warning about model type mismatch when loading + such checkpoints, which can be safely ignored in this case. + + + + Args: + vision_config (`dict` or `Sam3VisionConfig`, *optional*): + Configuration for the vision encoder. + text_config (`dict` or `Sam3TextConfig`, *optional*): + Configuration for the text encoder. + geometry_encoder_config (`dict` or `Sam3GeometryEncoderConfig`, *optional*): + Configuration for the geometry encoder. + detr_encoder_config (`dict` or `Sam3DETREncoderConfig`, *optional*): + Configuration for the DETR encoder. + detr_decoder_config (`dict` or `Sam3DETRDecoderConfig`, *optional*): + Configuration for the DETR decoder. + mask_decoder_config (`dict` or `Sam3MaskDecoderConfig`, *optional*): + Configuration for the mask decoder. + initializer_range (`float`, *optional*, defaults to 0.02): + The standard deviation of the truncated_normal_initializer for initializing weight matrices. + + Example: + ```python + >>> from transformers import Sam3Config, Sam3Model + + >>> # Initializing a SAM3 configuration + >>> configuration = Sam3Config() + + >>> # Initializing a model from the configuration + >>> model = Sam3Model(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ``` + """ + + model_type = "sam3" + is_composition = True + sub_configs = { + "vision_config": Sam3VisionConfig, + "text_config": CLIPTextConfig, + "geometry_encoder_config": Sam3GeometryEncoderConfig, + "detr_encoder_config": Sam3DETREncoderConfig, + "detr_decoder_config": Sam3DETRDecoderConfig, + "mask_decoder_config": Sam3MaskDecoderConfig, + } + + def __init__( + self, + vision_config=None, + text_config=None, + geometry_encoder_config=None, + detr_encoder_config=None, + detr_decoder_config=None, + mask_decoder_config=None, + initializer_range=0.02, + **kwargs, + ): + # Vision config + if vision_config is None: + vision_config = {} + if isinstance(vision_config, dict): + self.vision_config = Sam3VisionConfig(**vision_config) + else: + self.vision_config = vision_config + + # Text config (CLIPTextModelWithProjection defaults) + if text_config is None: + text_config = { + "vocab_size": 49408, + "hidden_size": 1024, + "intermediate_size": 4096, # hidden_size * mlp_ratio (1024 * 4) + "projection_dim": 512, # CLIP's internal projection dimension + "num_hidden_layers": 24, + "num_attention_heads": 16, + "max_position_embeddings": 32, + "hidden_act": "gelu", + } + if isinstance(text_config, dict): + self.text_config = CLIPTextConfig(**text_config) + else: + self.text_config = text_config + + # Geometry encoder config + if geometry_encoder_config is None: + geometry_encoder_config = {} + if isinstance(geometry_encoder_config, dict): + self.geometry_encoder_config = Sam3GeometryEncoderConfig(**geometry_encoder_config) + else: + self.geometry_encoder_config = geometry_encoder_config + + # DETR encoder config + if detr_encoder_config is None: + detr_encoder_config = {} + if isinstance(detr_encoder_config, dict): + self.detr_encoder_config = Sam3DETREncoderConfig(**detr_encoder_config) + else: + self.detr_encoder_config = detr_encoder_config + + # DETR decoder config + if detr_decoder_config is None: + detr_decoder_config = {} + if isinstance(detr_decoder_config, dict): + self.detr_decoder_config = Sam3DETRDecoderConfig(**detr_decoder_config) + else: + self.detr_decoder_config = detr_decoder_config + + # Mask decoder config + if mask_decoder_config is None: + mask_decoder_config = {} + if isinstance(mask_decoder_config, dict): + self.mask_decoder_config = Sam3MaskDecoderConfig(**mask_decoder_config) + else: + self.mask_decoder_config = mask_decoder_config + + self.initializer_range = initializer_range + super().__init__(**kwargs) + + @property + def image_size(self): + """Image size for the SAM3 model.""" + return self.vision_config.image_size + + @image_size.setter + def image_size(self, value): + """Set the image size and propagate to vision config.""" + self.vision_config.image_size = value + + +__all__ = [ + "Sam3Config", + "Sam3ViTConfig", + "Sam3VisionConfig", + "Sam3GeometryEncoderConfig", + "Sam3DETREncoderConfig", + "Sam3DETRDecoderConfig", + "Sam3MaskDecoderConfig", +] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam3/image_processing_sam3_fast.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam3/image_processing_sam3_fast.py new file mode 100644 index 0000000000000000000000000000000000000000..e896322fedc5b967fa2fb0bc3ae527a6c2eab07c --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam3/image_processing_sam3_fast.py @@ -0,0 +1,946 @@ +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# This file was automatically generated from src/transformers/models/sam3/modular_sam3.py. +# Do NOT edit this file manually as any edits will be overwritten by the generation of +# the file from the modular. If any change should be done, please apply the change to the +# modular_sam3.py file directly. One of our CI enforces this. +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# Copyright 2025 The Meta AI Authors and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + + +import math +from copy import deepcopy +from itertools import product +from typing import Any, Optional, Union + +import numpy as np +import torch +import torch.nn.functional as F +from torchvision.ops.boxes import batched_nms + +from ...image_processing_utils import BatchFeature, get_size_dict +from ...image_processing_utils_fast import BaseImageProcessorFast +from ...image_utils import ( + IMAGENET_STANDARD_MEAN, + IMAGENET_STANDARD_STD, + ChannelDimension, + ImageInput, + PILImageResampling, + SizeDict, + pil_torch_interpolation_mapping, +) +from ...processing_utils import ImagesKwargs, Unpack +from ...utils import TensorType, auto_docstring + + +class Sam3FastImageProcessorKwargs(ImagesKwargs, total=False): + r""" + mask_size (`dict[str, int]`, *optional*): + The size `{"height": int, "width": int}` to resize the segmentation maps to. + """ + + mask_size: dict[str, int] + + +def _compute_stability_score(masks: "torch.Tensor", mask_threshold: float, stability_score_offset: int): + # One mask is always contained inside the other. + # Save memory by preventing unnecessary cast to torch.int64 + intersections = ( + (masks > (mask_threshold + stability_score_offset)).sum(-1, dtype=torch.int16).sum(-1, dtype=torch.int32) + ) + unions = (masks > (mask_threshold - stability_score_offset)).sum(-1, dtype=torch.int16).sum(-1, dtype=torch.int32) + stability_scores = intersections / unions + return stability_scores + + +def _mask_to_rle(input_mask: "torch.Tensor"): + """ + Encodes masks the run-length encoding (RLE), in the format expected by pycoco tools. + """ + # Put in fortran order and flatten height and width + batch_size, height, width = input_mask.shape + input_mask = input_mask.permute(0, 2, 1).flatten(1) + + # Compute change indices + diff = input_mask[:, 1:] ^ input_mask[:, :-1] + change_indices = diff.nonzero() + + # Encode run length + out = [] + for i in range(batch_size): + cur_idxs = change_indices[change_indices[:, 0] == i, 1] + 1 + if len(cur_idxs) == 0: + # No changes => either all 0 or all 1 + # If the entire mask is 0, RLE is [height*width] or if the entire mask is 1, RLE is [0, height*width]. + if input_mask[i, 0] == 0: + out.append({"size": [height, width], "counts": [height * width]}) + else: + out.append({"size": [height, width], "counts": [0, height * width]}) + continue + btw_idxs = cur_idxs[1:] - cur_idxs[:-1] + counts = [] if input_mask[i, 0] == 0 else [0] + counts += [cur_idxs[0].item()] + btw_idxs.tolist() + [height * width - cur_idxs[-1].item()] + out.append({"size": [height, width], "counts": counts}) + return out + + +def _batched_mask_to_box(masks: "torch.Tensor"): + """ + Computes the bounding boxes around the given input masks. The bounding boxes are in the XYXY format which + corresponds the following required indices: + - LEFT: left hand side of the bounding box + - TOP: top of the bounding box + - RIGHT: right of the bounding box + - BOTTOM: bottom of the bounding box + + Return [0,0,0,0] for an empty mask. For input shape channel_1 x channel_2 x ... x height x width, the output shape + is channel_1 x channel_2 x ... x 4. + + Args: + - masks (`torch.Tensor` of shape `(batch, nb_mask, height, width)`) + """ + # torch.max below raises an error on empty inputs, just skip in this case + + if torch.numel(masks) == 0: + return torch.zeros(*masks.shape[:-2], 4, device=masks.device) + + # Normalize shape to Cxheightxwidth + shape = masks.shape + height, width = shape[-2:] + + # Get top and bottom edges + in_height, _ = torch.max(masks, dim=-1) + in_height_coords = in_height * torch.arange(height, device=in_height.device)[None, :] + bottom_edges, _ = torch.max(in_height_coords, dim=-1) + in_height_coords = in_height_coords + height * (~in_height) + top_edges, _ = torch.min(in_height_coords, dim=-1) + + # Get left and right edges + in_width, _ = torch.max(masks, dim=-2) + in_width_coords = in_width * torch.arange(width, device=in_width.device)[None, :] + right_edges, _ = torch.max(in_width_coords, dim=-1) + in_width_coords = in_width_coords + width * (~in_width) + left_edges, _ = torch.min(in_width_coords, dim=-1) + + # If the mask is empty the right edge will be to the left of the left edge. + # Replace these boxes with [0, 0, 0, 0] + empty_filter = (right_edges < left_edges) | (bottom_edges < top_edges) + out = torch.stack([left_edges, top_edges, right_edges, bottom_edges], dim=-1) + out = out * (~empty_filter).unsqueeze(-1) + + # Return to original shape + out = out.reshape(*shape[:-2], 4) + return out + + +def _is_box_near_crop_edge(boxes, crop_box, orig_box, atol=20.0): + """Filter masks at the edge of a crop, but not at the edge of the original image.""" + crop_box_torch = torch.as_tensor(crop_box, dtype=torch.float, device=boxes.device) + orig_box_torch = torch.as_tensor(orig_box, dtype=torch.float, device=boxes.device) + + left, top, _, _ = crop_box + offset = torch.tensor([[left, top, left, top]], device=boxes.device) + # Check if boxes has a channel dimension + if len(boxes.shape) == 3: + offset = offset.unsqueeze(1) + boxes = (boxes + offset).float() + + near_crop_edge = torch.isclose(boxes, crop_box_torch[None, :], atol=atol, rtol=0) + near_image_edge = torch.isclose(boxes, orig_box_torch[None, :], atol=atol, rtol=0) + near_crop_edge = torch.logical_and(near_crop_edge, ~near_image_edge) + return torch.any(near_crop_edge, dim=1) + + +def _pad_masks(masks, crop_box: list[int], orig_height: int, orig_width: int): + left, top, right, bottom = crop_box + if left == 0 and top == 0 and right == orig_width and bottom == orig_height: + return masks + # Coordinate transform masks + pad_x, pad_y = orig_width - (right - left), orig_height - (bottom - top) + pad = (left, pad_x - left, top, pad_y - top) + return torch.nn.functional.pad(masks, pad, value=0) + + +def _generate_crop_boxes( + image, + target_size: int, # Is it tuple here? + crop_n_layers: int = 0, + overlap_ratio: float = 512 / 1500, + points_per_crop: int | None = 32, + crop_n_points_downscale_factor: list[int] | None = 1, +) -> tuple[list[list[int]], list[int]]: + """ + Generates a list of crop boxes of different sizes. Each layer has (2**i)**2 boxes for the ith layer. + + Args: + image (Union[`numpy.ndarray`, `PIL.Image`, `torch.Tensor`]): + Image to generate crops for. + target_size (`int`): + Size of the smallest crop. + crop_n_layers (`int`, *optional*): + If `crops_n_layers>0`, mask prediction will be run again on crops of the image. Sets the number of layers + to run, where each layer has 2**i_layer number of image crops. + overlap_ratio (`int`, *optional*): + Sets the degree to which crops overlap. In the first crop layer, crops will overlap by this fraction of the + image length. Later layers with more crops scale down this overlap. + points_per_crop (`int`, *optional*): + Number of points to sam3ple per crop. + crop_n_points_downscale_factor (`int`, *optional*): + The number of points-per-side sam3pled in layer n is scaled down by crop_n_points_downscale_factor**n. + input_data_format (`str` or `ChannelDimension`, *optional*): + The channel dimension format of the input image. If not provided, it will be inferred. + """ + + if isinstance(image, list): + raise ValueError("Only one image is allowed for crop generation.") + original_size = image.shape[-2:] + + points_grid = [] + for i in range(crop_n_layers + 1): + n_points = int(points_per_crop / (crop_n_points_downscale_factor**i)) + points_grid.append(_build_point_grid(n_points)) + + crop_boxes, layer_idxs = _generate_per_layer_crops(crop_n_layers, overlap_ratio, original_size) + + cropped_images, point_grid_per_crop = _generate_crop_images( + crop_boxes, image, points_grid, layer_idxs, target_size, original_size + ) + crop_boxes = torch.tensor(crop_boxes) + crop_boxes = crop_boxes.float() + points_per_crop = torch.stack(point_grid_per_crop) + points_per_crop = points_per_crop.unsqueeze(0).permute(0, 2, 1, 3) + cropped_images = torch.stack(cropped_images) + + input_labels = torch.ones_like(points_per_crop[:, :, :, 0], dtype=torch.int64) + + return crop_boxes, points_per_crop, cropped_images, input_labels + + +def _generate_per_layer_crops(crop_n_layers, overlap_ratio, original_size): + """ + Generates 2 ** (layers idx + 1) crops for each crop_n_layers. Crops are in the XYWH format : The XYWH format + consists of the following required indices: + - X: X coordinate of the top left of the bounding box + - Y: Y coordinate of the top left of the bounding box + - W: width of the bounding box + - H: height of the bounding box + """ + crop_boxes, layer_idxs = [], [] + im_height, im_width = original_size + short_side = min(im_height, im_width) + + # Original image + crop_boxes.append([0, 0, im_width, im_height]) + layer_idxs.append(0) + for i_layer in range(crop_n_layers): + n_crops_per_side = 2 ** (i_layer + 1) + overlap = int(overlap_ratio * short_side * (2 / n_crops_per_side)) + + crop_width = int(math.ceil((overlap * (n_crops_per_side - 1) + im_width) / n_crops_per_side)) + crop_height = int(math.ceil((overlap * (n_crops_per_side - 1) + im_height) / n_crops_per_side)) + + crop_box_x0 = [int((crop_width - overlap) * i) for i in range(n_crops_per_side)] + crop_box_y0 = [int((crop_height - overlap) * i) for i in range(n_crops_per_side)] + + for left, top in product(crop_box_x0, crop_box_y0): + box = [left, top, min(left + crop_width, im_width), min(top + crop_height, im_height)] + crop_boxes.append(box) + layer_idxs.append(i_layer + 1) + + return crop_boxes, layer_idxs + + +def _build_point_grid(n_per_side: int) -> torch.Tensor: + """Generates a 2D grid of points evenly spaced in [0,1]x[0,1].""" + offset = 1 / (2 * n_per_side) + points_one_side = torch.linspace(offset, 1 - offset, n_per_side) + points_x = torch.tile(points_one_side[None, :], (n_per_side, 1)) + points_y = torch.tile(points_one_side[:, None], (1, n_per_side)) + points = torch.stack([points_x, points_y], dim=-1).reshape(-1, 2) + return points + + +def _generate_crop_images( + crop_boxes, image, points_grid, layer_idxs, target_size, original_size, input_data_format=None +): + """ + Takes as an input bounding boxes that are used to crop the image. Based in the crops, the corresponding points are + also passed. + """ + cropped_images = [] + total_points_per_crop = [] + for i, crop_box in enumerate(crop_boxes): + left, top, right, bottom = crop_box + cropped_im = image[:, top:bottom, left:right] + + cropped_images.append(cropped_im) + + cropped_im_size = cropped_im.shape[-2:] + points_scale = torch.tensor(cropped_im_size).flip(dims=(0,)).unsqueeze(0) + + points = points_grid[layer_idxs[i]] * points_scale + normalized_points = _normalize_coordinates(target_size, points, original_size) + total_points_per_crop.append(normalized_points) + + return cropped_images, total_points_per_crop + + +def _normalize_coordinates( + target_size: int, coords: torch.Tensor, original_size: tuple[int, int], is_bounding_box=False +) -> torch.Tensor: + """ + Expects a numpy array of length 2 in the final dimension. Requires the original image size in (height, width) + format. + """ + old_height, old_width = original_size + + scale = target_size * 1.0 / max(old_height, old_width) + new_height, new_width = old_height * scale, old_width * scale + new_width = int(new_width + 0.5) + new_height = int(new_height + 0.5) + + coords = deepcopy(coords).float() + + if is_bounding_box: + coords = coords.reshape(-1, 2, 2) + + coords[..., 0] = coords[..., 0] * (new_width / old_width) + coords[..., 1] = coords[..., 1] * (new_height / old_height) + + if is_bounding_box: + coords = coords.reshape(-1, 4) + + return coords + + +def _rle_to_mask(rle: dict[str, Any]) -> torch.Tensor: + """Compute a binary mask from an uncompressed RLE.""" + height, width = rle["size"] + mask = torch.empty(height * width, dtype=bool) + idx = 0 + parity = False + for count in rle["counts"]: + mask[idx : idx + count] = parity + idx += count + parity = not parity + mask = mask.reshape(width, height) + return mask.transpose(0, 1) # Reshape to original shape + + +def _post_process_for_mask_generation(rle_masks, iou_scores, mask_boxes, amg_crops_nms_thresh=0.7): + """ + Perform NMS (Non Maximum Suppression) on the outputs. + + Args: + rle_masks (`torch.Tensor`): + binary masks in the RLE format + iou_scores (`torch.Tensor` of shape (nb_masks, 1)): + iou_scores predicted by the model + mask_boxes (`torch.Tensor`): + The bounding boxes corresponding to segmentation masks + amg_crops_nms_thresh (`float`, *optional*, defaults to 0.7): + NMS threshold. + """ + keep_by_nms = batched_nms( + boxes=mask_boxes.float(), + scores=iou_scores, + idxs=torch.zeros(mask_boxes.shape[0]), + iou_threshold=amg_crops_nms_thresh, + ) + + iou_scores = iou_scores[keep_by_nms] + rle_masks = [rle_masks[i] for i in keep_by_nms] + mask_boxes = mask_boxes[keep_by_nms] + masks = [_rle_to_mask(rle) for rle in rle_masks] + + return masks, iou_scores, rle_masks, mask_boxes + + +def _scale_boxes(boxes, target_sizes): + """ + Scale batch of bounding boxes to the target sizes. + + Args: + boxes (`torch.Tensor` of shape `(batch_size, num_boxes, 4)`): + Bounding boxes to scale. Each box is expected to be in (x1, y1, x2, y2) format. + target_sizes (`list[tuple[int, int]]` or `torch.Tensor` of shape `(batch_size, 2)`): + Target sizes to scale the boxes to. Each target size is expected to be in (height, width) format. + + Returns: + `torch.Tensor` of shape `(batch_size, num_boxes, 4)`: Scaled bounding boxes. + """ + + if isinstance(target_sizes, (list, tuple)): + image_height = torch.tensor([i[0] for i in target_sizes]) + image_width = torch.tensor([i[1] for i in target_sizes]) + elif isinstance(target_sizes, torch.Tensor): + image_height, image_width = target_sizes.unbind(1) + else: + raise TypeError("`target_sizes` must be a list, tuple or torch.Tensor") + + scale_factor = torch.stack([image_width, image_height, image_width, image_height], dim=1) + scale_factor = scale_factor.unsqueeze(1).to(boxes.device) + boxes = boxes * scale_factor + return boxes + + +@auto_docstring +class Sam3ImageProcessorFast(BaseImageProcessorFast): + resample = PILImageResampling.BILINEAR + image_mean = IMAGENET_STANDARD_MEAN + image_std = IMAGENET_STANDARD_STD + size = {"height": 1008, "width": 1008} + mask_size = {"height": 288, "width": 288} + do_resize = True + do_rescale = True + do_normalize = True + do_convert_rgb = True + + valid_kwargs = Sam3FastImageProcessorKwargs + + # modular artefacts + do_pad = None + pad_size = None + mask_pad_size = None + + def __init__(self, **kwargs: Unpack[Sam3FastImageProcessorKwargs]): + super().__init__(**kwargs) + + def _further_process_kwargs( + self, + size: SizeDict | None = None, + mask_size: SizeDict | None = None, + default_to_square: bool | None = None, + image_mean: float | list[float] | None = None, + image_std: float | list[float] | None = None, + data_format: ChannelDimension | None = None, + **kwargs, + ) -> dict: + """ + Update kwargs that need further processing before being validated + Can be overridden by subclasses to customize the processing of kwargs. + """ + if kwargs is None: + kwargs = {} + if size is not None: + size = SizeDict(**get_size_dict(size=size, default_to_square=default_to_square)) + if mask_size is not None: + mask_size = SizeDict(**get_size_dict(mask_size, param_name="mask_size")) + if isinstance(image_mean, list): + image_mean = tuple(image_mean) + if isinstance(image_std, list): + image_std = tuple(image_std) + if data_format is None: + data_format = ChannelDimension.FIRST + + kwargs["size"] = size + kwargs["mask_size"] = mask_size + kwargs["image_mean"] = image_mean + kwargs["image_std"] = image_std + kwargs["data_format"] = data_format + + # torch resize uses interpolation instead of resample + # Check if resample is an int before checking if it's an instance of PILImageResampling + # because if pillow < 9.1.0, resample is an int and PILImageResampling is a module. + # Checking PILImageResampling will fail with error `TypeError: isinstance() arg 2 must be a type or tuple of types`. + resample = kwargs.pop("resample") + kwargs["interpolation"] = ( + pil_torch_interpolation_mapping[resample] if isinstance(resample, (PILImageResampling, int)) else resample + ) + + return kwargs + + @auto_docstring + def preprocess( + self, + images: ImageInput, + segmentation_maps: ImageInput | None = None, + **kwargs: Unpack[Sam3FastImageProcessorKwargs], + ) -> BatchFeature: + r""" + segmentation_maps (`ImageInput`, *optional*): + The segmentation maps to preprocess. + """ + return super().preprocess(images, segmentation_maps, **kwargs) + + def _preprocess_image_like_inputs( + self, + images: ImageInput, + segmentation_maps: ImageInput | None, + do_convert_rgb: bool, + input_data_format: ChannelDimension, + device: Union[str, "torch.device"] | None = None, + **kwargs: Unpack[Sam3FastImageProcessorKwargs], + ) -> BatchFeature: + """ + Preprocess image-like inputs. + """ + images = self._prepare_image_like_inputs( + images=images, do_convert_rgb=do_convert_rgb, input_data_format=input_data_format, device=device + ) + original_sizes = [image.shape[-2:] for image in images] + images_kwargs = kwargs.copy() + pixel_values = self._preprocess(images, **images_kwargs) + data = { + "pixel_values": pixel_values, + "original_sizes": original_sizes, + } + + if segmentation_maps is not None: + processed_segmentation_maps = self._prepare_image_like_inputs( + images=segmentation_maps, + expected_ndims=2, + do_convert_rgb=False, + input_data_format=ChannelDimension.FIRST, + ) + + segmentation_maps_kwargs = kwargs.copy() + segmentation_maps_kwargs.update( + { + "do_normalize": False, + "do_rescale": False, + "interpolation": pil_torch_interpolation_mapping[PILImageResampling.NEAREST], + "size": segmentation_maps_kwargs.pop("mask_size"), + } + ) + processed_segmentation_maps = self._preprocess( + images=processed_segmentation_maps, **segmentation_maps_kwargs + ) + data["labels"] = processed_segmentation_maps.squeeze(1).to(torch.int64) + + return BatchFeature(data=data, tensor_type=kwargs["return_tensors"]) + + def _preprocess( + self, + images: list["torch.Tensor"], + return_tensors: str | TensorType | None, + **kwargs, + ) -> "torch.Tensor": + return super()._preprocess(images, return_tensors=return_tensors, **kwargs).pixel_values + + def generate_crop_boxes( + self, + image: "torch.Tensor", + target_size, + crop_n_layers: int = 0, + overlap_ratio: float = 512 / 1500, + points_per_crop: int | None = 32, + crop_n_points_downscale_factor: list[int] | None = 1, + device: Optional["torch.device"] = None, + ): + """ + Generates a list of crop boxes of different sizes. Each layer has (2**i)**2 boxes for the ith layer. + + Args: + image (`torch.Tensor`): + Input original image + target_size (`int`): + Target size of the resized image + crop_n_layers (`int`, *optional*, defaults to 0): + If >0, mask prediction will be run again on crops of the image. Sets the number of layers to run, where + each layer has 2**i_layer number of image crops. + overlap_ratio (`float`, *optional*, defaults to 512/1500): + Sets the degree to which crops overlap. In the first crop layer, crops will overlap by this fraction of + the image length. Later layers with more crops scale down this overlap. + points_per_crop (`int`, *optional*, defaults to 32): + Number of points to sam3ple from each crop. + crop_n_points_downscale_factor (`list[int]`, *optional*, defaults to 1): + The number of points-per-side sam3pled in layer n is scaled down by crop_n_points_downscale_factor**n. + device (`torch.device`, *optional*, defaults to None): + Device to use for the computation. If None, cpu will be used. + input_data_format (`str` or `ChannelDimension`, *optional*): + The channel dimension format of the input image. If not provided, it will be inferred. + return_tensors (`str`, *optional*, defaults to `pt`): + If `pt`, returns `torch.Tensor`. + """ + image = self._process_image(image) + crop_boxes, points_per_crop, cropped_images, input_labels = _generate_crop_boxes( + image, + target_size, + crop_n_layers, + overlap_ratio, + points_per_crop, + crop_n_points_downscale_factor, + ) + if device is None: + device = torch.device("cpu") + crop_boxes = crop_boxes.to(device) + points_per_crop = points_per_crop.to(device) + # cropped_images stays as torch.Tensor + input_labels = input_labels.to(device) + + return crop_boxes, points_per_crop, cropped_images, input_labels + + def filter_masks( + self, + masks, + iou_scores, + original_size, + cropped_box_image, + pred_iou_thresh=0.88, + stability_score_thresh=0.95, + mask_threshold=0, + stability_score_offset=1, + ): + """ + Filters the predicted masks by selecting only the ones that meets several criteria. The first criterion being + that the iou scores needs to be greater than `pred_iou_thresh`. The second criterion is that the stability + score needs to be greater than `stability_score_thresh`. The method also converts the predicted masks to + bounding boxes and pad the predicted masks if necessary. + + Args: + masks (`torch.Tensor`): + Input masks. + iou_scores (`torch.Tensor`): + List of IoU scores. + original_size (`tuple[int,int]`): + Size of the original image. + cropped_box_image (`torch.Tensor`): + The cropped image. + pred_iou_thresh (`float`, *optional*, defaults to 0.88): + The threshold for the iou scores. + stability_score_thresh (`float`, *optional*, defaults to 0.95): + The threshold for the stability score. + mask_threshold (`float`, *optional*, defaults to 0): + The threshold for the predicted masks. + stability_score_offset (`float`, *optional*, defaults to 1): + The offset for the stability score used in the `_compute_stability_score` method. + + """ + original_height, original_width = original_size + iou_scores = iou_scores.flatten(0, 1) + masks = masks.flatten(0, 1) + + if masks.shape[0] != iou_scores.shape[0]: + raise ValueError("masks and iou_scores must have the sam3e batch size.") + + if masks.device != iou_scores.device: + iou_scores = iou_scores.to(masks.device) + + batch_size = masks.shape[0] + + keep_mask = torch.ones(batch_size, dtype=torch.bool, device=masks.device) + + if pred_iou_thresh > 0.0: + keep_mask = keep_mask & (iou_scores > pred_iou_thresh) + + # compute stability score + if stability_score_thresh > 0.0: + stability_scores = _compute_stability_score(masks, mask_threshold, stability_score_offset) + keep_mask = keep_mask & (stability_scores > stability_score_thresh) + + scores = iou_scores[keep_mask] + masks = masks[keep_mask] + + # binarize masks + masks = masks > mask_threshold + converted_boxes = _batched_mask_to_box(masks) + + keep_mask = ~_is_box_near_crop_edge( + converted_boxes, cropped_box_image, [0, 0, original_width, original_height] + ) + + scores = scores[keep_mask] + masks = masks[keep_mask] + converted_boxes = converted_boxes[keep_mask] + + masks = _pad_masks(masks, cropped_box_image, original_height, original_width) + # conversion to rle is necessary to run non-maximum suppression + masks = _mask_to_rle(masks) + + return masks, scores, converted_boxes + + def post_process_masks( + self, + masks, + original_sizes, + mask_threshold=0.0, + binarize=True, + max_hole_area=0.0, + max_sprinkle_area=0.0, + apply_non_overlapping_constraints=False, + **kwargs, + ): + """ + Remove padding and upscale masks to the original image size. + + Args: + masks (`Union[torch.Tensor, List[torch.Tensor], np.ndarray, List[np.ndarray]]`): + Batched masks from the mask_decoder in (batch_size, num_channels, height, width) format. + original_sizes (`Union[torch.Tensor, List[Tuple[int,int]]]`): + The original sizes of each image before it was resized to the model's expected input shape, in (height, + width) format. + mask_threshold (`float`, *optional*, defaults to 0.0): + Threshold for binarization and post-processing operations. + binarize (`bool`, *optional*, defaults to `True`): + Whether to binarize the masks. + max_hole_area (`float`, *optional*, defaults to 0.0): + The maximum area of a hole to fill. + max_sprinkle_area (`float`, *optional*, defaults to 0.0): + The maximum area of a sprinkle to fill. + apply_non_overlapping_constraints (`bool`, *optional*, defaults to `False`): + Whether to apply non-overlapping constraints to the masks. + + Returns: + (`torch.Tensor`): Batched masks in batch_size, num_channels, height, width) format, where (height, width) + is given by original_size. + """ + if isinstance(original_sizes, (torch.Tensor, np.ndarray)): + original_sizes = original_sizes.tolist() + # TODO: add connected components kernel for postprocessing + output_masks = [] + for i, original_size in enumerate(original_sizes): + if isinstance(masks[i], np.ndarray): + masks[i] = torch.from_numpy(masks[i]) + elif not isinstance(masks[i], torch.Tensor): + raise TypeError("Input masks should be a list of `torch.tensors` or a list of `np.ndarray`") + interpolated_mask = F.interpolate(masks[i], original_size, mode="bilinear", align_corners=False) + if apply_non_overlapping_constraints: + interpolated_mask = self._apply_non_overlapping_constraints(interpolated_mask) + if binarize: + interpolated_mask = interpolated_mask > mask_threshold + output_masks.append(interpolated_mask) + + return output_masks + + def post_process_for_mask_generation(self, all_masks, all_scores, all_boxes, crops_nms_thresh): + """ + Post processes mask that are generated by calling the Non Maximum Suppression algorithm on the predicted masks. + + Args: + all_masks (`torch.Tensor`): + List of all predicted segmentation masks + all_scores (`torch.Tensor`): + List of all predicted iou scores + all_boxes (`torch.Tensor`): + List of all bounding boxes of the predicted masks + crops_nms_thresh (`float`): + Threshold for NMS (Non Maximum Suppression) algorithm. + """ + return _post_process_for_mask_generation(all_masks, all_scores, all_boxes, crops_nms_thresh) + + def _apply_non_overlapping_constraints(self, pred_masks: torch.Tensor) -> torch.Tensor: + """ + Apply non-overlapping constraints to the object scores in pred_masks. Here we + keep only the highest scoring object at each spatial location in pred_masks. + """ + batch_size = pred_masks.size(0) + if batch_size == 1: + return pred_masks + + device = pred_masks.device + # "max_obj_inds": object index of the object with the highest score at each location + max_obj_inds = torch.argmax(pred_masks, dim=0, keepdim=True) + # "batch_obj_inds": object index of each object slice (along dim 0) in `pred_masks` + batch_obj_inds = torch.arange(batch_size, device=device)[:, None, None, None] + keep = max_obj_inds == batch_obj_inds + # suppress overlapping regions' scores below -10.0 so that the foreground regions + # don't overlap (here sigmoid(-10.0)=4.5398e-05) + pred_masks = torch.where(keep, pred_masks, torch.clamp(pred_masks, max=-10.0)) + return pred_masks + + def post_process_semantic_segmentation( + self, outputs, target_sizes: list[tuple] | None = None, threshold: float = 0.5 + ): + """ + Converts the output of [`Sam3Model`] into semantic segmentation maps. + + Args: + outputs ([`Sam3ImageSegmentationOutput`]): + Raw outputs of the model containing semantic_seg. + target_sizes (`list[tuple]` of length `batch_size`, *optional*): + List of tuples corresponding to the requested final size (height, width) of each prediction. If unset, + predictions will not be resized. + threshold (`float`, *optional*, defaults to 0.5): + Threshold for binarizing the semantic segmentation masks. + + Returns: + semantic_segmentation: `list[torch.Tensor]` of length `batch_size`, where each item is a semantic + segmentation map of shape (height, width) corresponding to the target_sizes entry (if `target_sizes` is + specified). Each entry is a binary mask (0 or 1). + """ + # Get semantic segmentation output + # semantic_seg has shape (batch_size, 1, height, width) + semantic_logits = outputs.semantic_seg + + if semantic_logits is None: + raise ValueError( + "Semantic segmentation output is not available in the model outputs. " + "Make sure the model was run with semantic segmentation enabled." + ) + + # Apply sigmoid to convert logits to probabilities + semantic_probs = semantic_logits.sigmoid() + + # Resize and binarize semantic segmentation maps + if target_sizes is not None: + if len(semantic_logits) != len(target_sizes): + raise ValueError( + "Make sure that you pass in as many target sizes as the batch dimension of the logits" + ) + + semantic_segmentation = [] + + for idx in range(len(semantic_logits)): + resized_probs = torch.nn.functional.interpolate( + semantic_probs[idx].unsqueeze(dim=0), + size=target_sizes[idx], + mode="bilinear", + align_corners=False, + ) + # Binarize: values > threshold become 1, otherwise 0 + semantic_map = (resized_probs[0, 0] > threshold).to(torch.long) + semantic_segmentation.append(semantic_map) + else: + # Binarize without resizing + semantic_segmentation = (semantic_probs[:, 0] > threshold).to(torch.long) + semantic_segmentation = [semantic_segmentation[i] for i in range(semantic_segmentation.shape[0])] + + return semantic_segmentation + + def post_process_object_detection(self, outputs, threshold: float = 0.3, target_sizes: list[tuple] | None = None): + """ + Converts the raw output of [`Sam3Model`] into final bounding boxes in (top_left_x, top_left_y, + bottom_right_x, bottom_right_y) format. + + Args: + outputs ([`Sam3ImageSegmentationOutput`]): + Raw outputs of the model containing pred_boxes, pred_logits, and optionally presence_logits. + threshold (`float`, *optional*, defaults to 0.3): + Score threshold to keep object detection predictions. + target_sizes (`list[tuple[int, int]]`, *optional*): + List of tuples (`tuple[int, int]`) containing the target size `(height, width)` of each image in the + batch. If unset, predictions will not be resized. + + Returns: + `list[dict]`: A list of dictionaries, each dictionary containing the following keys: + - **scores** (`torch.Tensor`): The confidence scores for each predicted box on the image. + - **boxes** (`torch.Tensor`): Image bounding boxes in (top_left_x, top_left_y, bottom_right_x, + bottom_right_y) format. + """ + pred_logits = outputs.pred_logits # (batch_size, num_queries) + pred_boxes = outputs.pred_boxes # (batch_size, num_queries, 4) in xyxy format + presence_logits = outputs.presence_logits # (batch_size, 1) or None + + batch_size = pred_logits.shape[0] + + if target_sizes is not None and len(target_sizes) != batch_size: + raise ValueError("Make sure that you pass in as many target sizes as images") + + # Compute scores: combine pred_logits with presence_logits if available + batch_scores = pred_logits.sigmoid() + if presence_logits is not None: + presence_scores = presence_logits.sigmoid() # (batch_size, 1) + batch_scores = batch_scores * presence_scores # Broadcast multiplication + + # Boxes are already in xyxy format from the model + batch_boxes = pred_boxes + + # Convert from relative [0, 1] to absolute [0, height/width] coordinates + if target_sizes is not None: + batch_boxes = _scale_boxes(batch_boxes, target_sizes) + + results = [] + for scores, boxes in zip(batch_scores, batch_boxes): + keep = scores > threshold + scores = scores[keep] + boxes = boxes[keep] + results.append({"scores": scores, "boxes": boxes}) + + return results + + def post_process_instance_segmentation( + self, + outputs, + threshold: float = 0.3, + mask_threshold: float = 0.5, + target_sizes: list[tuple] | None = None, + ): + """ + Converts the raw output of [`Sam3Model`] into instance segmentation predictions with bounding boxes and masks. + + Args: + outputs ([`Sam3ImageSegmentationOutput`]): + Raw outputs of the model containing pred_boxes, pred_logits, pred_masks, and optionally + presence_logits. + threshold (`float`, *optional*, defaults to 0.3): + Score threshold to keep instance predictions. + mask_threshold (`float`, *optional*, defaults to 0.5): + Threshold for binarizing the predicted masks. + target_sizes (`list[tuple[int, int]]`, *optional*): + List of tuples (`tuple[int, int]`) containing the target size `(height, width)` of each image in the + batch. If unset, predictions will not be resized. + + Returns: + `list[dict]`: A list of dictionaries, each dictionary containing the following keys: + - **scores** (`torch.Tensor`): The confidence scores for each predicted instance on the image. + - **boxes** (`torch.Tensor`): Image bounding boxes in (top_left_x, top_left_y, bottom_right_x, + bottom_right_y) format. + - **masks** (`torch.Tensor`): Binary segmentation masks for each instance, shape (num_instances, + height, width). + """ + pred_logits = outputs.pred_logits # (batch_size, num_queries) + pred_boxes = outputs.pred_boxes # (batch_size, num_queries, 4) in xyxy format + pred_masks = outputs.pred_masks # (batch_size, num_queries, height, width) + presence_logits = outputs.presence_logits # (batch_size, 1) or None + + batch_size = pred_logits.shape[0] + + if target_sizes is not None and len(target_sizes) != batch_size: + raise ValueError("Make sure that you pass in as many target sizes as images") + + # Compute scores: combine pred_logits with presence_logits if available + batch_scores = pred_logits.sigmoid() + if presence_logits is not None: + presence_scores = presence_logits.sigmoid() # (batch_size, 1) + batch_scores = batch_scores * presence_scores # Broadcast multiplication + + # Apply sigmoid to mask logits + batch_masks = pred_masks.sigmoid() + + # Boxes are already in xyxy format from the model + batch_boxes = pred_boxes + + # Scale boxes to target sizes if provided + if target_sizes is not None: + batch_boxes = _scale_boxes(batch_boxes, target_sizes) + + results = [] + for idx, (scores, boxes, masks) in enumerate(zip(batch_scores, batch_boxes, batch_masks)): + # Filter by score threshold + keep = scores > threshold + scores = scores[keep] + boxes = boxes[keep] + masks = masks[keep] # (num_keep, height, width) + + # Resize masks to target size if provided + if target_sizes is not None: + target_size = target_sizes[idx] + if len(masks) > 0: + masks = torch.nn.functional.interpolate( + masks.unsqueeze(0), # (1, num_keep, height, width) + size=target_size, + mode="bilinear", + align_corners=False, + ).squeeze(0) # (num_keep, target_height, target_width) + + # Binarize masks + masks = (masks > mask_threshold).to(torch.long) + + results.append({"scores": scores, "boxes": boxes, "masks": masks}) + + return results + + +__all__ = ["Sam3ImageProcessorFast"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam3/modeling_sam3.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam3/modeling_sam3.py new file mode 100644 index 0000000000000000000000000000000000000000..daad1e4fd51707cb4524084ef072cdfb24b8e4b8 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam3/modeling_sam3.py @@ -0,0 +1,2423 @@ +# Copyright 2025 The Meta AI Authors and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import math +from collections.abc import Callable, Iterable +from dataclasses import dataclass + +import numpy as np +import torch +import torch.nn as nn +import torch.nn.functional as F +import torchvision +from torch import Tensor + +from transformers import CLIPTextModelWithProjection + +from ... import initialization as init +from ...activations import ACT2FN +from ...masking_utils import create_bidirectional_mask +from ...modeling_layers import GradientCheckpointingLayer +from ...modeling_outputs import ( + BaseModelOutput, + BaseModelOutputWithPooling, + ModelOutput, +) +from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel +from ...processing_utils import Unpack +from ...pytorch_utils import compile_compatible_method_lru_cache +from ...utils import auto_docstring, can_return_tuple, logging +from ...utils.generic import ( + TransformersKwargs, + is_flash_attention_requested, + merge_with_config_defaults, +) +from ...utils.output_capturing import capture_outputs +from ..auto import AutoModel +from .configuration_sam3 import ( + Sam3Config, + Sam3DETRDecoderConfig, + Sam3DETREncoderConfig, + Sam3GeometryEncoderConfig, + Sam3MaskDecoderConfig, + Sam3VisionConfig, + Sam3ViTConfig, +) + + +logger = logging.get_logger(__name__) + + +@dataclass +@auto_docstring +class Sam3VisionEncoderOutput(BaseModelOutputWithPooling): + r""" + fpn_hidden_states (`tuple[torch.FloatTensor]`): + Tuple of multi-level FPN feature maps. + fpn_position_encoding (`tuple[torch.FloatTensor]`): + Tuple of position encodings for each FPN level. + """ + + fpn_hidden_states: tuple[torch.FloatTensor, ...] = None + fpn_position_encoding: tuple[torch.FloatTensor, ...] = None + + +@dataclass +@auto_docstring +class Sam3GeometryEncoderOutput(ModelOutput): + r""" + last_hidden_state (`torch.FloatTensor` of shape `(batch_size, num_prompts, hidden_size)`): + Encoded geometry prompt features (boxes). + attention_mask (`torch.BoolTensor` of shape `(batch_size, num_prompts)`, *optional*): + Attention mask for geometry prompts where True indicates valid positions and False indicates padding. + """ + + last_hidden_state: torch.FloatTensor = None + attention_mask: torch.BoolTensor | None = None + + +@dataclass +@auto_docstring +class Sam3DETREncoderOutput(ModelOutput): + r""" + last_hidden_state (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`): + Encoded vision features (flattened from multi-level features). + pos_embeds_flattened (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*): + Flattened position embeddings for the vision features. + text_features (`torch.FloatTensor` of shape `(batch_size, text_seq_len, hidden_size)`, *optional*): + Text features (may be pooled after encoder processing). + spatial_shapes (`torch.LongTensor` of shape `(num_levels, 2)`, *optional*): + Spatial shapes (height, width) for each feature pyramid level. + hidden_states (`tuple[torch.FloatTensor]`, *optional*): + Tuple of hidden states from all encoder layers. + attentions (`tuple[torch.FloatTensor]`, *optional*): + Tuple of attention weights from all encoder layers. + """ + + last_hidden_state: torch.FloatTensor = None + pos_embeds_flattened: torch.FloatTensor | None = None + text_features: torch.FloatTensor | None = None + spatial_shapes: torch.LongTensor | None = None + hidden_states: tuple[torch.FloatTensor] | None = None + attentions: tuple[torch.FloatTensor] | None = None + + +@dataclass +@auto_docstring +class Sam3DETRDecoderOutput(ModelOutput): + r""" + intermediate_hidden_states (`torch.FloatTensor` of shape `(num_layers, batch_size, num_queries, hidden_size)`): + Decoder hidden states from all layers. + reference_boxes (`torch.FloatTensor` of shape `(num_layers, batch_size, num_queries, 4)`): + Predicted reference boxes from all decoder layers in (cx, cy, w, h) format. + presence_logits (`torch.FloatTensor` of shape `(num_layers, batch_size, 1)`): + Presence logits from all decoder layers indicating object presence confidence. + hidden_states (`tuple[torch.FloatTensor]`, *optional*): + Tuple of hidden states from all decoder layers. + attentions (`tuple[torch.FloatTensor]`, *optional*): + Tuple of attention weights from all decoder layers (self-attention and cross-attention). + """ + + intermediate_hidden_states: torch.FloatTensor = None + reference_boxes: torch.FloatTensor = None + presence_logits: torch.FloatTensor = None + hidden_states: tuple[torch.FloatTensor] | None = None + attentions: tuple[torch.FloatTensor] | None = None + + +@dataclass +@auto_docstring +class Sam3MaskDecoderOutput(ModelOutput): + r""" + pred_masks (`torch.FloatTensor` of shape `(batch_size, num_queries, height, width)`): + Predicted segmentation masks for each query. + semantic_seg (`torch.FloatTensor` of shape `(batch_size, 1, height, width)`, *optional*): + Semantic segmentation output. + attentions (`tuple[torch.FloatTensor]`, *optional*): + Tuple of attention weights from mask decoder cross-attention layers. + """ + + pred_masks: torch.FloatTensor = None + semantic_seg: torch.FloatTensor | None = None + attentions: tuple[torch.FloatTensor] | None = None + + +@dataclass +@auto_docstring +class Sam3ImageSegmentationOutput(ModelOutput): + r""" + pred_masks (`torch.FloatTensor` of shape `(batch_size, num_queries, height, width)`): + Predicted segmentation masks for each query. + pred_boxes (`torch.FloatTensor` of shape `(batch_size, num_queries, 4)`): + Predicted bounding boxes in (x1, y1, x2, y2) format. + pred_logits (`torch.FloatTensor` of shape `(batch_size, num_queries)`, *optional*): + Classification confidence scores for each query, computed via dot product between + decoder query features and text features. + presence_logits (`torch.FloatTensor` of shape `(batch_size, 1)`, *optional*): + Presence logits from the DETR decoder presence token (last layer only). These indicate whether objects + are present in the scene. Can be used to compute final scores by multiplying with pred_logits: + `final_scores = pred_logits.sigmoid() * presence_logits.sigmoid()`. + semantic_seg (`torch.FloatTensor` of shape `(batch_size, 1, height, width)`, *optional*): + Semantic segmentation output. + decoder_hidden_states (`tuple[torch.FloatTensor]`, *optional*): + Tuple of hidden states from all DETR decoder layers. Each tensor has shape `(batch_size, num_queries, hidden_size)`. + decoder_reference_boxes (`torch.FloatTensor` of shape `(num_layers, batch_size, num_queries, 4)`, *optional*): + Reference boxes from all DETR decoder layers. + encoder_hidden_states (`tuple[torch.FloatTensor]`, *optional*): + Tuple of hidden states from all DETR encoder layers. + vision_hidden_states (`tuple[torch.FloatTensor]`, *optional*): + Tuple of hidden states from all vision encoder (ViT) layers. + vision_attentions (`tuple[torch.FloatTensor]`, *optional*): + Attention weights from vision encoder (ViT) layers. + detr_encoder_attentions (`tuple[torch.FloatTensor]`, *optional*): + Attention weights from DETR encoder layers. + detr_decoder_attentions (`tuple[torch.FloatTensor]`, *optional*): + Attention weights from DETR decoder layers (self-attention and cross-attention). + mask_decoder_attentions (`tuple[torch.FloatTensor]`, *optional*): + Attention weights from mask decoder layers. + """ + + pred_masks: torch.FloatTensor = None + pred_boxes: torch.FloatTensor = None + pred_logits: torch.FloatTensor | None = None + presence_logits: torch.FloatTensor | None = None + semantic_seg: torch.FloatTensor | None = None + decoder_hidden_states: tuple[torch.FloatTensor] | None = None + decoder_reference_boxes: torch.FloatTensor | None = None + encoder_hidden_states: tuple[torch.FloatTensor] | None = None + vision_hidden_states: tuple[torch.FloatTensor] | None = None + vision_attentions: tuple[torch.FloatTensor] | None = None + detr_encoder_attentions: tuple[torch.FloatTensor] | None = None + detr_decoder_attentions: tuple[torch.FloatTensor] | None = None + mask_decoder_attentions: tuple[torch.FloatTensor] | None = None + + +def inverse_sigmoid(x: torch.Tensor, eps: float = 1e-3) -> torch.Tensor: + """The inverse function for sigmoid activation function.""" + x = x.clamp(min=0, max=1) + x1 = x.clamp(min=eps) + x2 = (1 - x).clamp(min=eps) + return torch.log(x1 / x2) + + +def concat_padded_sequences(seq1, mask1, seq2, mask2, return_index: bool = False): + """ + Concatenates two right-padded sequences, such that the resulting sequence + is contiguous and also right-padded. + + Tensors are batch-first, masks are batch-first with True=valid, False=padding. + + Args: + seq1: A tensor of shape (batch_size, seq1_length, hidden_size). + mask1: A tensor of shape (batch_size, seq1_length) with True=valid, False=padding. + seq2: A tensor of shape (batch_size, seq2_length, hidden_size). + mask2: A tensor of shape (batch_size, seq2_length) with True=valid, False=padding. + return_index: If True, also returns the index of the ids of the element of seq2 + in the concatenated sequence. This can be used to retrieve the elements of seq2. + + Returns: + A tuple (concatenated_sequence, concatenated_mask) if return_index is False, + otherwise (concatenated_sequence, concatenated_mask, index). + The concatenated_mask uses True=valid, False=padding convention. + """ + batch_size, seq1_length, hidden_size = seq1.shape + batch_size2, seq2_length, hidden_size2 = seq2.shape + + assert batch_size == batch_size2 == mask1.size(0) == mask2.size(0) + assert hidden_size == hidden_size2 + assert seq1_length == mask1.size(1) + assert seq2_length == mask2.size(1) + + actual_seq1_lengths = mask1.sum(dim=-1) + actual_seq2_lengths = mask2.sum(dim=-1) + + final_lengths = actual_seq1_lengths + actual_seq2_lengths + max_length = seq1_length + seq2_length + + concatenated_mask = ( + torch.arange(max_length, device=seq2.device)[None].repeat(batch_size, 1) < final_lengths[:, None] + ) + + concatenated_sequence = torch.zeros((batch_size, max_length, hidden_size), device=seq2.device, dtype=seq2.dtype) + concatenated_sequence[:, :seq1_length, :] = seq1 + + # Shift seq2 elements to start at the end of valid seq1 + index = torch.arange(seq2_length, device=seq2.device)[None].repeat(batch_size, 1) + index = index + actual_seq1_lengths[:, None] + + # Scatter seq2 into the right positions + concatenated_sequence = concatenated_sequence.scatter(1, index[:, :, None].expand(-1, -1, hidden_size), seq2) + + if return_index: + return concatenated_sequence, concatenated_mask, index + + return concatenated_sequence, concatenated_mask + + +def box_cxcywh_to_xyxy(x): + """Convert boxes from (cx, cy, w, h) format to (x1, y1, x2, y2) format.""" + x_c, y_c, w, h = x.unbind(-1) + b = [(x_c - 0.5 * w), (y_c - 0.5 * h), (x_c + 0.5 * w), (y_c + 0.5 * h)] + return torch.stack(b, dim=-1) + + +class Sam3MLP(nn.Module): + def __init__(self, config: Sam3ViTConfig): + super().__init__() + self.config = config + self.activation_fn = ACT2FN[config.hidden_act] + self.fc1 = nn.Linear(config.hidden_size, config.intermediate_size) + self.fc2 = nn.Linear(config.intermediate_size, config.hidden_size) + self.dropout = nn.Dropout(config.hidden_dropout) + + def forward(self, hidden_states: torch.Tensor) -> torch.Tensor: + hidden_states = self.fc1(hidden_states) + hidden_states = self.dropout(hidden_states) + hidden_states = self.activation_fn(hidden_states) + hidden_states = self.fc2(hidden_states) + return hidden_states + + +def eager_attention_forward( + module: nn.Module, + query: torch.Tensor, + key: torch.Tensor, + value: torch.Tensor, + attention_mask: torch.Tensor | None, + scaling: float | None = None, + dropout: float = 0.0, + **kwargs: Unpack[TransformersKwargs], +): + if scaling is None: + scaling = query.size(-1) ** -0.5 + + # Take the dot product between "query" and "key" to get the raw attention scores. + attn_weights = torch.matmul(query, key.transpose(2, 3)) * scaling + + if attention_mask is not None: + attn_weights = attn_weights + attention_mask + + attn_weights = nn.functional.softmax(attn_weights, dim=-1) + attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training) + + attn_output = torch.matmul(attn_weights, value) + attn_output = attn_output.transpose(1, 2).contiguous() + + return attn_output, attn_weights + + +class Sam3Attention(nn.Module): + """ + Multi-head attention. + Handles standard [batch_size, seq_len, hidden_size] tensors. + """ + + def __init__(self, config): + super().__init__() + self.config = config + self.hidden_size = config.hidden_size + self.num_attention_heads = config.num_attention_heads + self.head_dim = self.hidden_size // config.num_attention_heads + self.scaling = self.head_dim**-0.5 + self.is_causal = False + + self.q_proj = nn.Linear(self.hidden_size, self.hidden_size) + self.k_proj = nn.Linear(self.hidden_size, self.hidden_size) + self.v_proj = nn.Linear(self.hidden_size, self.hidden_size) + self.o_proj = nn.Linear(self.hidden_size, self.hidden_size) + + def forward( + self, + query: torch.Tensor, + key: torch.Tensor, + value: torch.Tensor, + attention_mask: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor, torch.Tensor]: + """ + Args: + query: [batch_size, query_len, hidden_size] + key: [batch_size, key_len, hidden_size] + value: [batch_size, value_len, hidden_size] + attention_mask: [batch_size, num_heads, query_len, key_len] or broadcastable + + Returns: + Tuple of (output, attention_weights) + output: [batch_size, query_len, hidden_size] + attention_weights: [batch_size, num_heads, query_len, key_len] + """ + batch_size = query.shape[0] + query_len = query.shape[1] + key_len = key.shape[1] + + query = self.q_proj(query).view(batch_size, query_len, self.num_attention_heads, self.head_dim).transpose(1, 2) + key = self.k_proj(key).view(batch_size, key_len, self.num_attention_heads, self.head_dim).transpose(1, 2) + value = self.v_proj(value).view(batch_size, key_len, self.num_attention_heads, self.head_dim).transpose(1, 2) + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, eager_attention_forward + ) + + if ( + is_flash_attention_requested(self.config) + and attention_mask is not None + and attention_mask.dtype != torch.bool + ): + # Relative position bias tensors are represented as float masks and are incompatible with Flash Attention + # Fallback to SDPA for this call only so the rest of the model can still benefit from FA + attention_interface = ALL_ATTENTION_FUNCTIONS["sdpa"] + logger.warning_once( + "Sam3Attention: falling back to SDPA for relative-position cross-attention because " + "Flash Attention does not support additive bias masks." + ) + + attn_output, attn_weights = attention_interface( + self, + query, + key, + value, + attention_mask=attention_mask, + dropout=0.0, + scaling=self.scaling, + is_causal=self.is_causal, + **kwargs, + ) + + attn_output = attn_output.reshape(batch_size, query_len, self.num_attention_heads * self.head_dim).contiguous() + attn_output = self.o_proj(attn_output) + + return attn_output, attn_weights + + +class Sam3ViTRotaryEmbedding(nn.Module): + """ + Vision Rotary Position Embedding for SAM3, following transformers library standards. + Supports 2D (axial) rotary embeddings for spatial dimensions. + """ + + def __init__(self, config: Sam3ViTConfig, end_x: int, end_y: int, scale: float = 1.0): + super().__init__() + dim = config.hidden_size // config.num_attention_heads + # Ensure even dimension for proper axial splitting + if dim % 4 != 0: + raise ValueError("Dimension must be divisible by 4 for axial RoPE") + self.end_x, self.end_y = end_x, end_y + self.dim = dim + self.rope_theta = config.rope_theta + self.scale = scale + freqs = 1.0 / (config.rope_theta ** (torch.arange(0, dim, 4)[: (dim // 4)].float() / dim)) + + flattened_indices = torch.arange(end_x * end_y, dtype=torch.long) + x_positions = (flattened_indices % end_x) * scale + y_positions = torch.div(flattened_indices, end_x, rounding_mode="floor") * scale + freqs_x = torch.outer(x_positions, freqs).float() + freqs_y = torch.outer(y_positions, freqs).float() + inv_freq = torch.cat([freqs_x, freqs_y], dim=-1) + inv_freq = inv_freq.repeat_interleave(2, dim=-1) + # directly register the cos and sin embeddings as we have a fixed feature shape + self.register_buffer("rope_embeddings_cos", inv_freq.cos(), persistent=False) + self.register_buffer("rope_embeddings_sin", inv_freq.sin(), persistent=False) + + @torch.no_grad() + def forward(self) -> tuple[torch.Tensor, torch.Tensor]: + # As the feature map size is fixed for each stage, we can just return the pre-computed embeddings. + return self.rope_embeddings_cos, self.rope_embeddings_sin + + +def rotate_pairwise(x): + """ + pairwise rotation of the hidden dims of the input. Differerent from Llama Half-Tensor Rotation. + + This is an optimized version of the following more explicit implementation: + ```python + x_rotated = torch.zeros_like(x, dtype=x.dtype, device=x.device) + x_rotated[..., ::2] = -x[..., 1::2] + x_rotated[..., 1::2] = x[..., ::2] + return x_rotated + ``` + """ + x = x.view(*x.shape[:-1], -1, 2) + x1, x2 = x.unbind(dim=-1) + x = torch.stack((-x2, x1), dim=-1) + return x.flatten(start_dim=-2) + + +def apply_rotary_pos_emb_2d( + q: torch.Tensor, + k: torch.Tensor, + cos: torch.Tensor, + sin: torch.Tensor, +) -> tuple[torch.Tensor, torch.Tensor]: + """ + Apply rotary position embedding to query and key tensors for self-attention. + + Args: + q: Query tensor of shape (batch_size, num_windows, seq_len, num_heads, head_dim) + k: Key tensor of shape (batch_size, num_windows, seq_len, num_heads, head_dim) + cos: Cosine position embedding of shape (seq_len, head_dim) + sin: Sine position embedding of shape (seq_len, head_dim) + + Returns: + Rotated (q, k) tensors + """ + q_embed = q.float() + q_embed = (q_embed * cos) + (rotate_pairwise(q_embed) * sin) + + k_embed = k.float() + k_embed = (k_embed * cos) + (rotate_pairwise(k_embed) * sin) + + return q_embed.type_as(q), k_embed.type_as(k) + + +class Sam3ViTRoPEAttention(nn.Module): + """Self-attention with rotary position encoding.""" + + def __init__(self, config: Sam3ViTConfig): + super().__init__() + self.config = config + self.hidden_size = config.hidden_size + self.num_attention_heads = config.num_attention_heads + self.head_dim = self.hidden_size // config.num_attention_heads + self.scaling = self.head_dim**-0.5 + self.attention_dropout = config.attention_dropout + self.is_causal = False + + self.q_proj = nn.Linear(self.hidden_size, self.hidden_size) + self.k_proj = nn.Linear(self.hidden_size, self.hidden_size) + self.v_proj = nn.Linear(self.hidden_size, self.hidden_size) + self.o_proj = nn.Linear(self.hidden_size, self.hidden_size) + + def forward( + self, + hidden_states: torch.Tensor, + position_embeddings: tuple[torch.Tensor, torch.Tensor], + **kwargs: Unpack[TransformersKwargs], + ) -> Tensor: + batch_size, height, width, _ = hidden_states.shape + seq_len = height * width + new_shape = (batch_size, seq_len, self.num_attention_heads, self.head_dim) + query = self.q_proj(hidden_states).view(*new_shape).transpose(1, 2) + key = self.k_proj(hidden_states).view(*new_shape).transpose(1, 2) + value = self.v_proj(hidden_states).view(*new_shape).transpose(1, 2) + cos, sin = position_embeddings + query, key = apply_rotary_pos_emb_2d(query, key, cos=cos, sin=sin) + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, eager_attention_forward + ) + + attn_output, attn_weights = attention_interface( + self, + query, + key, + value, + attention_mask=None, + dropout=0.0 if not self.training else self.attention_dropout, + scaling=self.scaling, + is_causal=self.is_causal, + **kwargs, + ) + attn_output = attn_output.reshape(batch_size, height, width, -1).contiguous() + attn_output = self.o_proj(attn_output) + return attn_output, attn_weights + + +class Sam3ViTPatchEmbeddings(nn.Module): + """ + This class turns `pixel_values` of shape `(batch_size, num_channels, height, width)` into the initial + `hidden_states` (patch embeddings) of shape `(batch_size, seq_length, hidden_size)` to be consumed by a + Transformer. + """ + + def __init__(self, config: Sam3ViTConfig): + super().__init__() + image_size, patch_size = config.pretrain_image_size, config.patch_size + num_channels, hidden_size = config.num_channels, config.hidden_size + + image_size = image_size if isinstance(image_size, Iterable) else (image_size, image_size) + patch_size = patch_size if isinstance(patch_size, Iterable) else (patch_size, patch_size) + num_patches = (image_size[1] // patch_size[1]) * (image_size[0] // patch_size[0]) + self.image_size = image_size + self.patch_size = patch_size + self.num_channels = num_channels + self.num_patches = num_patches + + self.projection = nn.Conv2d(num_channels, hidden_size, kernel_size=patch_size, stride=patch_size, bias=False) + + def forward(self, pixel_values: torch.Tensor) -> torch.Tensor: + embeddings = self.projection(pixel_values.to(self.projection.weight.dtype)).flatten(2).transpose(1, 2) + return embeddings + + +class Sam3ViTEmbeddings(nn.Module): + """ + Construct the patch embeddings and position embeddings for SAM3 ViT. + + Position embeddings are tiled (not interpolated) when resizing to match different input sizes. + """ + + def __init__(self, config: Sam3ViTConfig): + super().__init__() + + self.patch_embeddings = Sam3ViTPatchEmbeddings(config) + num_patches = self.patch_embeddings.num_patches + self.position_embeddings = nn.Parameter( + torch.randn(1, num_patches, config.hidden_size) + ) # !Remove cls token in convert weights! + + self.dropout = nn.Dropout(config.hidden_dropout) + self.patch_size = config.patch_size + + def _tile_position_embeddings( + self, + position_embeddings: torch.Tensor, + height: int, + width: int, + ) -> torch.Tensor: + """ + Tile position embeddings to match target spatial dimensions. + Args: + position_embeddings: Shape [1, num_pretrain_patches, hidden_size] + height: Target height in patches + width: Target width in patches + + Returns: + Shape [1, height * width, hidden_size] + """ + pretrain_size = int(position_embeddings.shape[1] ** 0.5) + + # Skip tiling if sizes match (but always tile during tracing for consistent graph) + if not torch.jit.is_tracing() and pretrain_size == height and pretrain_size == width: + return position_embeddings.reshape(1, height * width, -1) + + # Tile position embeddings to match target spatial dimensions + hidden_size = position_embeddings.shape[-1] + pos_embed = position_embeddings.reshape(1, pretrain_size, pretrain_size, hidden_size).permute(0, 3, 1, 2) + repeat_h = height // pretrain_size + 1 + repeat_w = width // pretrain_size + 1 + pos_embed = pos_embed.tile([1, 1, repeat_h, repeat_w])[:, :, :height, :width] + return pos_embed.permute(0, 2, 3, 1).reshape(1, height * width, hidden_size) + + def forward( + self, + pixel_values: torch.Tensor, + interpolate_pos_encoding: bool = False, + ) -> torch.Tensor: + height, width = pixel_values.shape[-2:] + embeddings = self.patch_embeddings(pixel_values) + + # Calculate spatial dimensions in patches + height_patches = height // self.patch_size + width_patches = width // self.patch_size + + position_embeddings = self._tile_position_embeddings( + self.position_embeddings, + height_patches, + width_patches, + ) + embeddings = embeddings + position_embeddings + embeddings = self.dropout(embeddings) + + return embeddings + + +def window_partition(hidden_state, window_size): + """ + Partition into non-overlapping windows with padding if needed. + + Args: + hidden_state (`torch.Tensor`): + Input tokens with [batch_size, height, width, num_channels]. + window_size (`int`): + Window size. + + Returns: + `tuple(torch.FloatTensor)` comprising various elements: + - windows: windows after partition with [batch_size * num_windows, window_size, window_size, num_channels]. + - (padded_height, padded_width): padded height and width before partition + """ + batch_size, height, width, num_channels = hidden_state.shape + pad_height = (window_size - height % window_size) % window_size + pad_width = (window_size - width % window_size) % window_size + + # Noop in case pad_width == 0 and pad_height == 0. + hidden_state = nn.functional.pad(hidden_state, (0, 0, 0, pad_width, 0, pad_height)) + + padded_height, padded_width = height + pad_height, width + pad_width + + hidden_state = hidden_state.view( + batch_size, padded_height // window_size, window_size, padded_width // window_size, window_size, num_channels + ) + windows = hidden_state.permute(0, 1, 3, 2, 4, 5).contiguous().view(-1, window_size, window_size, num_channels) + return windows, (padded_height, padded_width) + + +def window_unpartition(windows, window_size, pad_height_width, height_width): + """ + Window unpartition into original sequences and removing padding. + + Args: + windows (`torch.Tensor`): + Input tokens with [batch_size * num_windows, window_size, window_size, num_channels]. + window_size (`int`): + Window size. + pad_height_width (`tuple[int]`): + Padded height and width (padded_height, padded_width). + height_width (`tuple[int]`): + Original height and width before padding. + + Returns: + hidden_state: unpartitioned sequences with [batch_size, height, width, num_channels]. + """ + padded_height, padded_width = pad_height_width + height, width = height_width + batch_size = windows.shape[0] // (padded_height * padded_width // window_size // window_size) + hidden_state = windows.view( + batch_size, padded_height // window_size, padded_width // window_size, window_size, window_size, -1 + ) + hidden_state = hidden_state.permute(0, 1, 3, 2, 4, 5).contiguous() + hidden_state = hidden_state.view(batch_size, padded_height, padded_width, -1) + + # We always have height <= padded_height and width <= padded_width + hidden_state = hidden_state[:, :height, :width, :].contiguous() + return hidden_state + + +class Sam3ViTLayerScale(nn.Module): + def __init__(self, config) -> None: + super().__init__() + self.lambda1 = nn.Parameter(config.layer_scale_init_value * torch.ones(config.hidden_size)) + + def forward(self, hidden_state: torch.Tensor) -> torch.Tensor: + return hidden_state * self.lambda1 + + +class Sam3ViTLayer(GradientCheckpointingLayer): + """Vision Transformer layer with rotary position embeddings and optional windowed attention.""" + + def __init__(self, config: Sam3ViTConfig, window_size: int = 0) -> None: + super().__init__() + + hidden_size = config.hidden_size + image_size = config.image_size + image_size = image_size if isinstance(image_size, (list, tuple)) else (image_size, image_size) + + patch_size = config.patch_size + patch_size = patch_size if isinstance(patch_size, (list, tuple)) else (patch_size, patch_size) + + input_size = (image_size[0] // patch_size[0], image_size[1] // patch_size[1]) + self.layer_norm1 = nn.LayerNorm(hidden_size, eps=config.layer_norm_eps) + rotary_input_size = input_size if window_size == 0 else (window_size, window_size) + rotary_scale = config.window_size / rotary_input_size[0] + self.rotary_emb = Sam3ViTRotaryEmbedding( + config, end_x=rotary_input_size[0], end_y=rotary_input_size[1], scale=rotary_scale + ) + self.attention = Sam3ViTRoPEAttention(config) + self.layer_norm2 = nn.LayerNorm(hidden_size, eps=config.layer_norm_eps) + self.mlp = Sam3MLP(config) + self.dropout = nn.Dropout(config.hidden_dropout) + + self.window_size = window_size + + def forward( + self, + hidden_states: torch.Tensor, + **kwargs: Unpack[TransformersKwargs], + ) -> torch.Tensor: + residual = hidden_states + + hidden_states = self.layer_norm1(hidden_states) + + if self.window_size > 0: + height, width = hidden_states.shape[1], hidden_states.shape[2] + # Partition into non-overlapping windows for efficient attention + hidden_states, pad_height_width = window_partition(hidden_states, self.window_size) + + position_embeddings = self.rotary_emb() + hidden_states, _ = self.attention(hidden_states, position_embeddings, **kwargs) + + if self.window_size > 0: + # Reverse window partition to restore original spatial layout + hidden_states = window_unpartition(hidden_states, self.window_size, pad_height_width, (height, width)) + + hidden_states = residual + hidden_states + residual = hidden_states + hidden_states = self.layer_norm2(hidden_states) + hidden_states = self.mlp(hidden_states) + hidden_states = residual + self.dropout(hidden_states) + + return hidden_states + + +@auto_docstring +class Sam3PreTrainedModel(PreTrainedModel): + config_class = Sam3Config + base_model_prefix = "sam3" + main_input_name = "pixel_values" + input_modalities = ["image", "text"] + _supports_sdpa = True + _supports_flash_attn = True + _supports_flex_attn = True + _supports_attention_backend = True + + def _init_weights(self, module): + super()._init_weights(module) + if isinstance(module, Sam3ViTEmbeddings): + init.normal_(module.position_embeddings, mean=0.0, std=self.config.initializer_range) + elif isinstance(module, Sam3ViTRotaryEmbedding): + end_x, end_y = module.end_x, module.end_y + dim = module.dim + freqs = 1.0 / (module.rope_theta ** (torch.arange(0, dim, 4)[: (dim // 4)].float() / dim)) + flattened_indices = torch.arange(end_x * end_y, dtype=torch.long) + x_positions = (flattened_indices % end_x) * module.scale + y_positions = torch.div(flattened_indices, end_x, rounding_mode="floor") * module.scale + freqs_x = torch.outer(x_positions, freqs).float() + freqs_y = torch.outer(y_positions, freqs).float() + inv_freq = torch.cat([freqs_x, freqs_y], dim=-1) + inv_freq = inv_freq.repeat_interleave(2, dim=-1) + init.copy_(module.rope_embeddings_cos, inv_freq.cos()) + init.copy_(module.rope_embeddings_sin, inv_freq.sin()) + + +@auto_docstring +class Sam3ViTModel(Sam3PreTrainedModel): + _can_record_outputs = { + "hidden_states": Sam3ViTLayer, + "attentions": Sam3ViTRoPEAttention, + } + + def __init__(self, config: Sam3ViTConfig): + super().__init__(config) + self.config = config + self.embeddings = Sam3ViTEmbeddings(config) + self.layer_norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps) + self.layers = nn.ModuleList( + [ + Sam3ViTLayer(config, window_size=config.window_size if i not in config.global_attn_indexes else 0) + for i in range(config.num_hidden_layers) + ] + ) + self.post_init() + + def get_input_embeddings(self) -> Sam3ViTPatchEmbeddings: + return self.embeddings.patch_embeddings + + @merge_with_config_defaults + @capture_outputs(tie_last_hidden_states=False) + @auto_docstring + def forward( + self, + pixel_values: torch.Tensor, + **kwargs: Unpack[TransformersKwargs], + ) -> BaseModelOutput: + hidden_states = self.embeddings(pixel_values) # [batch_size, seq_len, hidden_size] + + batch_size = hidden_states.shape[0] + height = pixel_values.shape[-2] // self.config.patch_size + width = pixel_values.shape[-1] // self.config.patch_size + hidden_size = hidden_states.shape[-1] + + # Reshape to spatial format for windowed attention: [batch_size, height, width, hidden_size] + hidden_states = hidden_states.view(batch_size, height, width, hidden_size) + + hidden_states = self.layer_norm(hidden_states) + for layer in self.layers: + hidden_states = layer(hidden_states, **kwargs) + + # Reshape back to sequence format: [batch_size, height*width, hidden_size] + hidden_states = hidden_states.view(batch_size, height * width, hidden_size) + + return BaseModelOutput(last_hidden_state=hidden_states) + + +class Sam3SinePositionEmbedding(nn.Module): + """ + This is a more standard version of the position embedding, very similar to the one used by the Attention is all you + need paper, generalized to work on images. + """ + + def __init__( + self, num_pos_feats: int = 64, temperature: int = 10000, normalize: bool = False, scale: float | None = None + ): + super().__init__() + if scale is not None and normalize is False: + raise ValueError("normalize should be True if scale is passed") + self.num_pos_feats = num_pos_feats + self.temperature = temperature + self.normalize = normalize + self.scale = 2 * math.pi if scale is None else scale + + def encode_1d_positions(self, x: torch.Tensor, y: torch.Tensor) -> tuple[torch.Tensor, torch.Tensor]: + """ + Encode 1D coordinate pairs using sine/cosine positional embeddings. + + Args: + x: 1D tensor of x coordinates (flattened) + y: 1D tensor of y coordinates (flattened) + + Returns: + Tuple of (pos_x, pos_y) positional embeddings + """ + x_embed = x * self.scale + y_embed = y * self.scale + + dim_t = torch.arange(self.num_pos_feats, dtype=torch.int64, device=x.device).to(x.dtype) + dim_t = self.temperature ** (2 * (dim_t // 2) / self.num_pos_feats) + + pos_x = x_embed[:, None] / dim_t + pos_y = y_embed[:, None] / dim_t + pos_x = torch.stack((pos_x[:, 0::2].sin(), pos_x[:, 1::2].cos()), dim=2).flatten(1) + pos_y = torch.stack((pos_y[:, 0::2].sin(), pos_y[:, 1::2].cos()), dim=2).flatten(1) + return pos_x, pos_y + + def encode_boxes(self, boxes: torch.Tensor) -> torch.Tensor: + """ + Encode 4D box coordinates (x, y, w, h) for decoder conditioning using sine/cosine embeddings. + + Args: + boxes: Box coordinates [batch_size, num_queries, 4] in (x, y, w, h) format + + Returns: + Position embeddings [batch_size, num_queries, num_pos_feats*4] + """ + assert boxes.size(-1) == 4, f"Expected 4D box coordinates (x, y, w, h), got shape {boxes.shape}" + dim_t = torch.arange(self.num_pos_feats, dtype=torch.int64, device=boxes.device).to(boxes.dtype) + dim_t = self.temperature ** (2 * torch.div(dim_t, 2, rounding_mode="floor") / self.num_pos_feats) + + x_embed = boxes[:, :, 0] * self.scale + y_embed = boxes[:, :, 1] * self.scale + w_embed = boxes[:, :, 2] * self.scale + h_embed = boxes[:, :, 3] * self.scale + + pos_x = x_embed[:, :, None] / dim_t + pos_y = y_embed[:, :, None] / dim_t + pos_w = w_embed[:, :, None] / dim_t + pos_h = h_embed[:, :, None] / dim_t + + pos_x = torch.stack((pos_x[:, :, 0::2].sin(), pos_x[:, :, 1::2].cos()), dim=3).flatten(2) + pos_y = torch.stack((pos_y[:, :, 0::2].sin(), pos_y[:, :, 1::2].cos()), dim=3).flatten(2) + pos_w = torch.stack((pos_w[:, :, 0::2].sin(), pos_w[:, :, 1::2].cos()), dim=3).flatten(2) + pos_h = torch.stack((pos_h[:, :, 0::2].sin(), pos_h[:, :, 1::2].cos()), dim=3).flatten(2) + + pos = torch.cat((pos_y, pos_x, pos_w, pos_h), dim=2) + + return pos + + @compile_compatible_method_lru_cache(maxsize=4) + def forward( + self, + shape: torch.Size, + device: torch.device | str, + dtype: torch.dtype, + mask: Tensor | None = None, + ) -> Tensor: + if mask is None: + mask = torch.zeros((shape[0], shape[2], shape[3]), device=device, dtype=torch.bool) + not_mask = (~mask).to(dtype) + y_embed = not_mask.cumsum(1) + x_embed = not_mask.cumsum(2) + if self.normalize: + eps = 1e-6 + y_embed = y_embed / (y_embed[:, -1:, :] + eps) * self.scale + x_embed = x_embed / (x_embed[:, :, -1:] + eps) * self.scale + + dim_t = torch.arange(self.num_pos_feats, dtype=torch.int64, device=device).to(dtype) + dim_t = self.temperature ** (2 * torch.div(dim_t, 2, rounding_mode="floor") / self.num_pos_feats) + + pos_x = x_embed[:, :, :, None] / dim_t + pos_y = y_embed[:, :, :, None] / dim_t + pos_x = torch.stack((pos_x[:, :, :, 0::2].sin(), pos_x[:, :, :, 1::2].cos()), dim=4).flatten(3) + pos_y = torch.stack((pos_y[:, :, :, 0::2].sin(), pos_y[:, :, :, 1::2].cos()), dim=4).flatten(3) + pos = torch.cat((pos_y, pos_x), dim=3).permute(0, 3, 1, 2) + return pos + + +class Sam3FPNLayer(nn.Module): + def __init__(self, in_channels: int, fpn_dim: int, scale_factor: float): + super().__init__() + self.scale_factor = scale_factor + + # Build the upsampling/downsampling layers based on scale factor + self.scale_layers = nn.ModuleList() + + if scale_factor == 4.0: + self.scale_layers.append(nn.ConvTranspose2d(in_channels, in_channels // 2, kernel_size=2, stride=2)) + self.scale_layers.append(nn.GELU()) + self.scale_layers.append(nn.ConvTranspose2d(in_channels // 2, in_channels // 4, kernel_size=2, stride=2)) + intermediate_channels = in_channels // 4 + elif scale_factor == 2.0: + self.scale_layers.append(nn.ConvTranspose2d(in_channels, in_channels // 2, kernel_size=2, stride=2)) + intermediate_channels = in_channels // 2 + elif scale_factor == 1.0: + intermediate_channels = in_channels + elif scale_factor == 0.5: + self.scale_layers.append(nn.MaxPool2d(kernel_size=2, stride=2)) + intermediate_channels = in_channels + else: + raise NotImplementedError(f"scale_factor={scale_factor} is not supported yet.") + + self.proj1 = nn.Conv2d(in_channels=intermediate_channels, out_channels=fpn_dim, kernel_size=1) + self.proj2 = nn.Conv2d(in_channels=fpn_dim, out_channels=fpn_dim, kernel_size=3, padding=1) + + def forward(self, hidden_states: torch.Tensor) -> torch.Tensor: + hidden_states = hidden_states.to(self.proj1.weight.dtype) + for layer in self.scale_layers: + hidden_states = layer(hidden_states) + + hidden_states = self.proj1(hidden_states) + hidden_states = self.proj2(hidden_states) + + return hidden_states + + +class Sam3VisionNeck(nn.Module): + def __init__(self, config: Sam3VisionConfig): + super().__init__() + self.config = config + + self.position_encoding = Sam3SinePositionEmbedding(num_pos_feats=config.fpn_hidden_size // 2, normalize=True) + + # Create one FPN layer per scale factor + self.fpn_layers = nn.ModuleList( + [ + Sam3FPNLayer( + in_channels=config.backbone_config.hidden_size, fpn_dim=config.fpn_hidden_size, scale_factor=scale + ) + for scale in config.scale_factors + ] + ) + + def forward(self, hidden_states: torch.Tensor) -> tuple[tuple[torch.Tensor, ...], tuple[torch.Tensor, ...]]: + fpn_hidden_states = () + fpn_position_encoding = () + + for fpn_layer in self.fpn_layers: + fpn_output = fpn_layer(hidden_states) + fpn_hidden_states += (fpn_output,) + # Generate position encoding for this FPN level + pos_enc = self.position_encoding(fpn_output.shape, fpn_output.device, fpn_output.dtype) + fpn_position_encoding += (pos_enc,) + + return fpn_hidden_states, fpn_position_encoding + + +@auto_docstring( + custom_intro=""" + The vision model from Sam without any head or projection on top. + """ +) +class Sam3VisionModel(Sam3PreTrainedModel): + config_class = Sam3VisionConfig + main_input_name = "pixel_values" + + def __init__(self, config: Sam3VisionConfig): + super().__init__(config) + self.config = config + self.backbone = AutoModel.from_config(config.backbone_config) + self.neck = Sam3VisionNeck(config) + + self.post_init() + + def get_input_embeddings(self): + return self.backbone.get_input_embeddings() + + @can_return_tuple + def forward( + self, + pixel_values: torch.FloatTensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple | Sam3VisionEncoderOutput: + if pixel_values is None: + raise ValueError("You have to specify pixel_values") + + backbone_output = self.backbone(pixel_values, **kwargs) + hidden_states = backbone_output.last_hidden_state # [batch_size, seq_len, hidden_size] + + # Reshape for FPN neck: [batch_size, seq_len, hidden_size] -> [batch_size, hidden_size, height, width] + batch_size = hidden_states.shape[0] + height = pixel_values.shape[-2] // self.config.backbone_config.patch_size + width = pixel_values.shape[-1] // self.config.backbone_config.patch_size + hidden_states_spatial = hidden_states.view(batch_size, height, width, -1).permute(0, 3, 1, 2) + fpn_hidden_states, fpn_position_encoding = self.neck(hidden_states_spatial) + + return Sam3VisionEncoderOutput( + last_hidden_state=hidden_states, + fpn_hidden_states=fpn_hidden_states, + fpn_position_encoding=fpn_position_encoding, + hidden_states=backbone_output.hidden_states, + attentions=backbone_output.attentions, + ) + + +class Sam3GeometryEncoderLayer(nn.Module): + def __init__(self, config: Sam3GeometryEncoderConfig): + super().__init__() + self.layer_norm1 = nn.LayerNorm(config.hidden_size) + self.self_attn = Sam3Attention(config) + self.dropout = nn.Dropout(config.dropout) + + self.cross_attn = Sam3Attention(config) + self.layer_norm2 = nn.LayerNorm(config.hidden_size) + + self.mlp = Sam3MLP(config) + self.layer_norm3 = nn.LayerNorm(config.hidden_size) + + def forward( + self, + prompt_feats: Tensor, + vision_feats: Tensor, + vision_pos_encoding: Tensor, + prompt_mask: Tensor, + **kwargs: Unpack[TransformersKwargs], + ): + residual = prompt_feats + hidden_states = self.layer_norm1(prompt_feats) + hidden_states, _ = self.self_attn( + query=hidden_states, key=hidden_states, value=hidden_states, attention_mask=prompt_mask, **kwargs + ) + hidden_states = self.dropout(hidden_states) + residual + residual = hidden_states + hidden_states = self.layer_norm2(hidden_states) + key = vision_feats + vision_pos_encoding + hidden_states, _ = self.cross_attn(query=hidden_states, key=key, value=vision_feats, **kwargs) + hidden_states = self.dropout(hidden_states) + residual + residual = hidden_states + hidden_states = self.layer_norm3(hidden_states) + hidden_states = self.mlp(hidden_states) + hidden_states = self.dropout(hidden_states) + residual + + return hidden_states + + +class Sam3GeometryEncoder(nn.Module): + """ + Encoder for geometric prompts (boxes). + + Boxes are encoded using three approaches: + - Direct projection: linear projection from coordinate space to hidden_size + - Pooling: pool features from the backbone at the specified location (ROI align for boxes) + - Position encoding: use position encoding of the box center + + These encodings are combined additively and further processed with transformer layers. + """ + + def __init__(self, config: Sam3GeometryEncoderConfig): + super().__init__() + self.config = config + self.hidden_size = config.hidden_size + self.roi_size = config.roi_size + + self.position_encoding = Sam3SinePositionEmbedding(num_pos_feats=config.hidden_size // 2, normalize=True) + self.label_embed = nn.Embedding(2, self.hidden_size) + self.cls_embed = nn.Embedding(1, self.hidden_size) + + # Box encoding layers + self.boxes_direct_project = nn.Linear(4, self.hidden_size) + self.boxes_pool_project = nn.Conv2d(self.hidden_size, self.hidden_size, self.roi_size) + self.boxes_pos_enc_project = nn.Linear(self.hidden_size + 2, self.hidden_size) + + # Image feature normalization + self.vision_layer_norm = nn.LayerNorm(self.hidden_size) + + # Prompt projection and normalization + self.final_proj = nn.Linear(self.hidden_size, self.hidden_size) + self.prompt_layer_norm = nn.LayerNorm(self.hidden_size) + + # Transformer layers + self.layers = nn.ModuleList([Sam3GeometryEncoderLayer(config) for _ in range(config.num_layers)]) + self.output_layer_norm = nn.LayerNorm(self.hidden_size) + + def _encode_box_coordinates( + self, center_x: torch.Tensor, center_y: torch.Tensor, width: torch.Tensor, height: torch.Tensor + ) -> torch.Tensor: + """ + Encode box coordinates by combining position-encoded centers with raw width/height. + + Args: + center_x: 1D tensor of box center x coordinates + center_y: 1D tensor of box center y coordinates + width: 1D tensor of box widths + height: 1D tensor of box heights + + Returns: + Encoded box coordinates [N, embedding_dim] + """ + pos_x, pos_y = self.position_encoding.encode_1d_positions(center_x, center_y) + pos = torch.cat((pos_y, pos_x, height[:, None], width[:, None]), dim=1) + return pos + + def _encode_boxes(self, boxes, boxes_mask, boxes_labels, vision_features): + """Encode box prompts. Mask convention: True=valid, False=padding.""" + batch_size, num_boxes = boxes.shape[:2] + height, width = vision_features.shape[-2:] + boxes_embed = self.boxes_direct_project(boxes) + + # Pool features using ROI align + # Convert boxes from CxCyWH to xyxy format and denormalize + boxes_xyxy = box_cxcywh_to_xyxy(boxes) + scale = torch.tensor([width, height, width, height], dtype=boxes_xyxy.dtype, device=boxes_xyxy.device) + scale = scale.view(1, 1, 4) + boxes_xyxy = boxes_xyxy * scale + # ROI align expects list of boxes per batch element, + # convert from bfloat16 to float16 as roi_align only supports float16 and float32 + dtype = torch.float16 if vision_features.dtype == torch.bfloat16 else vision_features.dtype + sampled_features = torchvision.ops.roi_align( + vision_features.to(dtype), boxes_xyxy.to(dtype).unbind(0), self.roi_size + ).to(vision_features.dtype) + + pooled_projection = self.boxes_pool_project(sampled_features) + pooled_projection = pooled_projection.view(batch_size, num_boxes, self.hidden_size) + boxes_embed = boxes_embed + pooled_projection + + # Add position encoding + center_x, center_y, box_width, box_height = boxes.unbind(-1) + pos_enc = self._encode_box_coordinates( + center_x.flatten(), center_y.flatten(), box_width.flatten(), box_height.flatten() + ) + pos_enc = pos_enc.view(batch_size, num_boxes, pos_enc.shape[-1]) + pos_projection = self.boxes_pos_enc_project(pos_enc) + boxes_embed = boxes_embed + pos_projection + + # Add label embeddings (positive/negative) + label_embed = self.label_embed(boxes_labels.long()) + return label_embed + boxes_embed, boxes_mask + + def forward( + self, + box_embeddings: torch.Tensor, + box_mask: torch.Tensor, + box_labels: torch.Tensor, + img_feats: tuple[torch.Tensor, ...], + img_pos_embeds: tuple[torch.Tensor, ...] | None = None, + ): + """ + Forward pass for encoding geometric prompts. + + Args: + box_embeddings: Box coordinates in CxCyWH format [batch_size, num_boxes, 4] + box_mask: Attention mask for boxes [batch_size, num_boxes] + box_labels: Labels for boxes (positive/negative) [batch_size, num_boxes] + img_feats: Image features from vision encoder + img_pos_embeds: Optional position embeddings for image features + + Returns: + Sam3GeometryEncoderOutput containing encoded geometry features and attention mask. + """ + batch_size = box_embeddings.shape[0] + + # Prepare vision features for cross-attention: flatten spatial dimensions + vision_feats = img_feats[-1] # [B, C, H, W] + vision_pos_embeds = img_pos_embeds[-1] if img_pos_embeds is not None else torch.zeros_like(vision_feats) + vision_feats_flat = vision_feats.flatten(2).transpose(1, 2) # [B, H*W, C] + vision_pos_embeds_flat = vision_pos_embeds.flatten(2).transpose(1, 2) # [B, H*W, C] + + # Normalize image features for pooling operations + img_feats_last = img_feats[-1] # [B, C, H, W] + img_feats_last = img_feats_last.permute(0, 2, 3, 1) # [B, H, W, C] + normalized_img_feats = self.vision_layer_norm(img_feats_last) + normalized_img_feats = normalized_img_feats.permute(0, 3, 1, 2) # [B, C, H, W] + + prompt_embeds, prompt_mask = self._encode_boxes(box_embeddings, box_mask, box_labels, normalized_img_feats) + + # Add CLS token (always valid) + cls_embed = self.cls_embed.weight.view(1, self.hidden_size).unsqueeze(0).expand(batch_size, -1, -1) + cls_mask = torch.ones(batch_size, 1, dtype=prompt_mask.dtype, device=prompt_mask.device) + prompt_embeds, prompt_mask = concat_padded_sequences(prompt_embeds, prompt_mask, cls_embed, cls_mask) + + prompt_embeds = self.prompt_layer_norm(self.final_proj(prompt_embeds)) + + # Create bidirectional attention mask for transformer layers + prompt_attention_mask = None + if prompt_mask is not None: + prompt_attention_mask = create_bidirectional_mask( + config=self.config, + inputs_embeds=prompt_embeds, + attention_mask=prompt_mask, + ) + + # Apply transformer layers with cross-attention to vision features + for layer in self.layers: + prompt_embeds = layer( + prompt_feats=prompt_embeds, + vision_feats=vision_feats_flat, + vision_pos_encoding=vision_pos_embeds_flat, + prompt_mask=prompt_attention_mask, + ) + + # Final output normalization + prompt_embeds = self.output_layer_norm(prompt_embeds) + + return Sam3GeometryEncoderOutput( + last_hidden_state=prompt_embeds, + attention_mask=prompt_mask, + ) + + +class Sam3DetrEncoderLayer(nn.Module): + """DETR encoder layer with self-attention and cross-attention.""" + + def __init__(self, config: Sam3DETREncoderConfig): + super().__init__() + self.config = config + self.layer_norm1 = nn.LayerNorm(config.hidden_size) + self.self_attn = Sam3Attention(config) + self.dropout = nn.Dropout(config.dropout) + + self.cross_attn = Sam3Attention(config) + self.layer_norm2 = nn.LayerNorm(config.hidden_size) + + self.mlp = Sam3MLP(config) + self.layer_norm3 = nn.LayerNorm(config.hidden_size) + + def forward( + self, + vision_feats: Tensor, + prompt_feats: Tensor, + vision_pos_encoding: Tensor, + prompt_cross_attn_mask: Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ): + """ + Forward pass for DETR encoder layer. + + Args: + vision_feats: Vision features [batch_size, vision_len, hidden_size] (main hidden states) + prompt_feats: Text prompt features [batch_size, text_len, hidden_size] + vision_pos_encoding: Position encoding for vision [batch_size, vision_len, hidden_size] + prompt_cross_attn_mask: Cross-attention mask for prompt features + + Returns: + Updated vision features [batch_size, vision_len, hidden_size] + """ + # Self-attention on vision features with position encoding + residual = vision_feats + hidden_states = self.layer_norm1(vision_feats) + hidden_states_with_pos = hidden_states + vision_pos_encoding + hidden_states, _ = self.self_attn( + query=hidden_states_with_pos, + key=hidden_states_with_pos, + value=hidden_states, + **kwargs, + ) + hidden_states = self.dropout(hidden_states) + residual + + # Cross-attention: vision queries attend to text/prompt features + residual = hidden_states + hidden_states = self.layer_norm2(hidden_states) + + hidden_states, _ = self.cross_attn( + query=hidden_states, + key=prompt_feats, + value=prompt_feats, + attention_mask=prompt_cross_attn_mask, + **kwargs, + ) + hidden_states = self.dropout(hidden_states) + residual + + # MLP + residual = hidden_states + hidden_states = self.layer_norm3(hidden_states) + hidden_states = self.mlp(hidden_states) + hidden_states = self.dropout(hidden_states) + residual + + return hidden_states + + +class Sam3DetrEncoder(Sam3PreTrainedModel): + """ + DETR-style encoder that processes multi-level vision features with text fusion. + + This encoder processes vision features from multiple levels (e.g., FPN features at different + resolutions) and fuses them with text prompts through a stack of transformer encoder layers. + """ + + _can_record_outputs = { + "hidden_states": Sam3DetrEncoderLayer, + "attentions": Sam3Attention, + } + + def __init__(self, config: Sam3DETREncoderConfig): + super().__init__(config) + self.config = config + self.hidden_size = config.hidden_size + + self.layers = nn.ModuleList([Sam3DetrEncoderLayer(config) for _ in range(config.num_layers)]) + + self.post_init() + + def _prepare_multilevel_features( + self, + vision_features: list[torch.Tensor], + vision_pos_embeds: list[torch.Tensor], + ): + """ + Prepare multi-level vision features by flattening spatial dimensions and adding level embeddings. + + Args: + vision_features: List of vision features at different levels [batch_size, channels, height, width] + vision_pos_embeds: List of position embeddings for each level [batch_size, channels, height, width] + + Returns: + Tuple containing flattened features, position embeddings, and spatial metadata + """ + features_flattened = [] + pos_embeds_flattened = [] + spatial_shapes = [] + + for features, pos_embed in zip(vision_features, vision_pos_embeds): + height, width = features.shape[-2:] + spatial_shapes.append((height, width)) + + # Flatten spatial dimensions: [batch_size, channels, height, width] -> [batch_size, height*width, channels] + features = features.flatten(2).transpose(1, 2) + pos_embed = pos_embed.flatten(2).transpose(1, 2) + + features_flattened.append(features) + pos_embeds_flattened.append(pos_embed) + + # Concatenate all levels into single sequence + features_flattened = torch.cat(features_flattened, dim=1) + pos_embeds_flattened = torch.cat(pos_embeds_flattened, dim=1) + + spatial_shapes = torch.tensor(spatial_shapes, dtype=torch.long, device=features_flattened.device) + + return ( + features_flattened, + pos_embeds_flattened, + spatial_shapes, + ) + + @merge_with_config_defaults + @capture_outputs + def forward( + self, + vision_features: list[torch.Tensor], + text_features: torch.Tensor, + vision_pos_embeds: list[torch.Tensor] | None = None, + text_mask: torch.Tensor | None = None, + spatial_sizes: list[tuple[int, int]] | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple | Sam3DETREncoderOutput: + """ + Forward pass for the DETR encoder. + + Args: + vision_features: List of vision features at different levels + text_features: Text prompt features [batch_size, seq_len, hidden_size] + vision_pos_embeds: Optional list of position embeddings for each level + text_mask: Optional text padding mask [batch_size, seq_len] + spatial_sizes: Optional list of (height, width) tuples for reshaping + + Returns: + Sam3DETREncoderOutput containing encoded features and metadata. + """ + batch_size = vision_features[0].shape[0] if vision_features[0].dim() == 4 else vision_features[0].shape[1] + + # TODO: See if we can remove that reshaping and just use the features as is. + if spatial_sizes is not None: + for i, (height, width) in enumerate(spatial_sizes): + # Reshape from [height*width, batch_size, channels] to [batch_size, channels, height, width] + vision_features[i] = vision_features[i].reshape(height, width, batch_size, -1).permute(2, 3, 0, 1) + vision_pos_embeds[i] = vision_pos_embeds[i].reshape(height, width, batch_size, -1).permute(2, 3, 0, 1) + + # Flatten multi-level features for encoder processing + ( + features_flattened, + pos_embeds_flattened, + spatial_shapes, + ) = self._prepare_multilevel_features(vision_features, vision_pos_embeds) + + prompt_cross_attn_mask = None + if text_mask is not None: + prompt_cross_attn_mask = create_bidirectional_mask( + config=self.config, + inputs_embeds=features_flattened, + attention_mask=text_mask, + encoder_hidden_states=text_features, + ) + + hidden_states = features_flattened + for layer in self.layers: + hidden_states = layer( + hidden_states, + prompt_feats=text_features, + vision_pos_encoding=pos_embeds_flattened, + prompt_cross_attn_mask=prompt_cross_attn_mask, + **kwargs, + ) + return Sam3DETREncoderOutput( + last_hidden_state=hidden_states, + pos_embeds_flattened=pos_embeds_flattened, + text_features=text_features, + spatial_shapes=spatial_shapes, + ) + + +class Sam3DecoderMLP(nn.Module): + """Simple 2 or 3-layer MLP for decoder components.""" + + def __init__(self, input_dim: int, hidden_dim: int, output_dim: int, num_layers: int = 2): + super().__init__() + if num_layers == 2: + self.layer1 = nn.Linear(input_dim, hidden_dim) + self.layer2 = nn.Linear(hidden_dim, output_dim) + self.layer3 = None + elif num_layers == 3: + self.layer1 = nn.Linear(input_dim, hidden_dim) + self.layer2 = nn.Linear(hidden_dim, hidden_dim) + self.layer3 = nn.Linear(hidden_dim, output_dim) + else: + raise ValueError(f"Only 2 or 3 layers supported, got {num_layers}") + + def forward(self, x: torch.Tensor) -> torch.Tensor: + x = F.relu(self.layer1(x)) + if self.layer3 is not None: + x = F.relu(self.layer2(x)) + x = self.layer3(x) + else: + x = self.layer2(x) + return x + + +class Sam3DetrDecoderLayer(nn.Module): + """DETR decoder layer with self-attention, text cross-attention, and vision cross-attention.""" + + def __init__(self, config: Sam3DETRDecoderConfig): + super().__init__() + self.config = config + self.self_attn = Sam3Attention(config) + self.self_attn_dropout = nn.Dropout(config.dropout) + self.self_attn_layer_norm = nn.LayerNorm(config.hidden_size) + + self.text_cross_attn = Sam3Attention(config) + self.text_cross_attn_dropout = nn.Dropout(config.dropout) + self.text_cross_attn_layer_norm = nn.LayerNorm(config.hidden_size) + + self.vision_cross_attn = Sam3Attention(config) + self.vision_cross_attn_dropout = nn.Dropout(config.dropout) + self.vision_cross_attn_layer_norm = nn.LayerNorm(config.hidden_size) + + self.mlp = Sam3MLP(config) + self.mlp_layer_norm = nn.LayerNorm(config.hidden_size) + self.mlp_dropout = nn.Dropout(config.dropout) + + def forward( + self, + hidden_states: torch.Tensor, + query_pos: torch.Tensor, + text_features: torch.Tensor, + vision_features: torch.Tensor, + vision_pos_encoding: torch.Tensor, + text_cross_attn_mask: torch.Tensor | None = None, + vision_cross_attn_mask: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> torch.Tensor: + """ + Forward pass for decoder layer. + + Args: + hidden_states: Query features [batch_size, num_queries + 1, hidden_size] (includes presence token at position 0) + query_pos: Query position embeddings [batch_size, num_queries, hidden_size] + text_features: Text features [batch_size, seq_len, hidden_size] + vision_features: Vision features [batch_size, height*width, hidden_size] + vision_pos_encoding: Vision position encoding [batch_size, height*width, hidden_size] + text_cross_attn_mask: Text cross-attention mask + vision_cross_attn_mask: Vision cross-attention mask, already expanded for presence token + + Returns: + Updated hidden states (including presence token at position 0) + """ + # Prepend zeros to query_pos for presence token + query_pos = F.pad(query_pos, (0, 0, 1, 0), mode="constant", value=0) + + # Self-attention with query position encoding + residual = hidden_states + query_with_pos = hidden_states + query_pos + attn_output, _ = self.self_attn( + query=query_with_pos, + key=query_with_pos, + value=hidden_states, + attention_mask=None, + **kwargs, + ) + hidden_states = residual + self.self_attn_dropout(attn_output) + hidden_states = self.self_attn_layer_norm(hidden_states) + + # Text cross-attention: queries attend to text features + residual = hidden_states + query_with_pos = hidden_states + query_pos + + attn_output, _ = self.text_cross_attn( + query=query_with_pos, + key=text_features, + value=text_features, + attention_mask=text_cross_attn_mask, + **kwargs, + ) + hidden_states = residual + self.text_cross_attn_dropout(attn_output) + hidden_states = self.text_cross_attn_layer_norm(hidden_states) + + # Vision cross-attention: queries attend to vision features (with RPB) + residual = hidden_states + query_with_pos = hidden_states + query_pos + key_with_pos = vision_features + vision_pos_encoding + attn_output, _ = self.vision_cross_attn( + query=query_with_pos, + key=key_with_pos, + value=vision_features, + attention_mask=vision_cross_attn_mask, + **kwargs, + ) + hidden_states = residual + self.vision_cross_attn_dropout(attn_output) + hidden_states = self.vision_cross_attn_layer_norm(hidden_states) + + # MLP + residual = hidden_states + hidden_states = self.mlp(hidden_states) + hidden_states = residual + self.mlp_dropout(hidden_states) + hidden_states = self.mlp_layer_norm(hidden_states) + + return hidden_states + + +class Sam3DetrDecoder(Sam3PreTrainedModel): + """ + DETR-style decoder with box refinement and presence token. + + Simplified version that assumes: + - Box refinement is always enabled + - Intermediate outputs are always returned + - BoxRPB (relative position bias) with log-scale encoding + - Presence token is used + """ + + _can_record_outputs = { + "hidden_states": Sam3DetrDecoderLayer, + "attentions": Sam3Attention, + } + + def __init__( + self, + config: Sam3DETRDecoderConfig, + ): + super().__init__(config) + self.config = config + self.hidden_size = config.hidden_size + + self.layers = nn.ModuleList([Sam3DetrDecoderLayer(config) for _ in range(config.num_layers)]) + + self.output_layer_norm = nn.LayerNorm(config.hidden_size) + + self.box_head = Sam3DecoderMLP(config.hidden_size, config.hidden_size, 4, 3) + + self.query_embed = nn.Embedding(config.num_queries, config.hidden_size) + self.reference_points = nn.Embedding(config.num_queries, 4) + + self.presence_token = nn.Embedding(1, config.hidden_size) + self.presence_head = Sam3DecoderMLP(config.hidden_size, config.hidden_size, 1, 3) + self.presence_layer_norm = nn.LayerNorm(config.hidden_size) + self.clamp_presence_logit_max_val = 10.0 + + self.ref_point_head = Sam3DecoderMLP(2 * config.hidden_size, config.hidden_size, config.hidden_size, 2) + + self.box_rpb_embed_x = Sam3DecoderMLP(2, config.hidden_size, config.num_attention_heads, 2) + self.box_rpb_embed_y = Sam3DecoderMLP(2, config.hidden_size, config.num_attention_heads, 2) + + self.position_encoding = Sam3SinePositionEmbedding(num_pos_feats=config.hidden_size // 2, normalize=False) + + self.post_init() + + @compile_compatible_method_lru_cache(maxsize=1) + def _get_coords( + self, height: torch.Tensor, width: torch.Tensor, dtype: torch.dtype, device: torch.device + ) -> tuple[torch.Tensor, torch.Tensor]: + """Generate normalized coordinate grids.""" + coords_h = torch.arange(0, height, device=device, dtype=dtype) / height + coords_w = torch.arange(0, width, device=device, dtype=dtype) / width + return coords_h, coords_w + + def _get_rpb_matrix( + self, reference_boxes: torch.Tensor, spatial_shape: tuple[torch.Tensor, torch.Tensor] + ) -> torch.Tensor: + """ + Compute box relative position bias (RPB) matrix using log-scale encoding. + RPB helps the decoder attend to relevant spatial locations based on predicted box positions. + + Args: + reference_boxes: Reference boxes [batch_size, num_queries, 4] in sigmoid space + spatial_shape: (height, width) of the vision features as tensors + + Returns: + RPB matrix [batch_size, num_heads, num_queries, height*width] + """ + height, width = spatial_shape + boxes_xyxy = box_cxcywh_to_xyxy(reference_boxes) + batch_size, num_queries, _ = boxes_xyxy.shape + + # Generate coordinate grids + coords_h, coords_w = self._get_coords( + height, width, dtype=reference_boxes.dtype, device=reference_boxes.device + ) + + # Compute deltas between coordinates and box boundaries + deltas_y = coords_h.view(1, -1, 1) - boxes_xyxy.reshape(-1, 1, 4)[:, :, 1:4:2] + deltas_y = deltas_y.view(batch_size, num_queries, -1, 2) + deltas_x = coords_w.view(1, -1, 1) - boxes_xyxy.reshape(-1, 1, 4)[:, :, 0:3:2] + deltas_x = deltas_x.view(batch_size, num_queries, -1, 2) + + # Apply log-scale encoding + deltas_x_log = deltas_x * 8 + deltas_x_log = torch.sign(deltas_x_log) * torch.log2(torch.abs(deltas_x_log) + 1.0) / math.log2(8) + deltas_y_log = deltas_y * 8 + deltas_y_log = torch.sign(deltas_y_log) * torch.log2(torch.abs(deltas_y_log) + 1.0) / math.log2(8) + + # Embed deltas + deltas_x = self.box_rpb_embed_x(deltas_x_log) # [batch_size, num_queries, width, num_heads] + deltas_y = self.box_rpb_embed_y(deltas_y_log) # [batch_size, num_queries, height, num_heads] + + # Combine into 2D bias matrix + rpb_matrix = deltas_y.unsqueeze(3) + deltas_x.unsqueeze( + 2 + ) # [batch_size, num_queries, height, width, num_heads] + rpb_matrix = rpb_matrix.flatten(2, 3) # [batch_size, num_queries, height*width, num_heads] + rpb_matrix = rpb_matrix.permute(0, 3, 1, 2).contiguous() # [batch_size, num_heads, num_queries, height*width] + return rpb_matrix + + @merge_with_config_defaults + @capture_outputs + def forward( + self, + vision_features: torch.Tensor, + text_features: torch.Tensor, + vision_pos_encoding: torch.Tensor, + text_mask: torch.Tensor | None = None, + spatial_shapes: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple | Sam3DETRDecoderOutput: + """ + Forward pass for the DETR decoder. + + Args: + vision_features: Vision features [batch_size, height*width, hidden_size] + text_features: Text features [batch_size, seq_len, hidden_size] + vision_pos_encoding: Vision position encoding [batch_size, height*width, hidden_size] + text_mask: Text padding mask [batch_size, seq_len] where True=valid, False=padding + spatial_shapes: Spatial shapes [num_levels, 2] + + Returns: + Sam3DETRDecoderOutput containing decoder outputs from all layers. + """ + batch_size = vision_features.shape[0] + + query_embeds = self.query_embed.weight.unsqueeze(0).expand(batch_size, -1, -1) + reference_boxes = self.reference_points.weight.unsqueeze(0).expand(batch_size, -1, -1) + reference_boxes = reference_boxes.sigmoid() + presence_token = self.presence_token.weight.unsqueeze(0).expand(batch_size, -1, -1) + + # Concatenate presence token with query embeddings + hidden_states = torch.cat([presence_token, query_embeds], dim=1) + + text_cross_attn_mask = None + if text_mask is not None: + text_cross_attn_mask = create_bidirectional_mask( + config=self.config, + inputs_embeds=hidden_states, + attention_mask=text_mask, + encoder_hidden_states=text_features, + ) + + intermediate_outputs = [] + intermediate_boxes = [reference_boxes] + intermediate_presence_logits = [] + + for layer in self.layers: + # Generate sine embeddings for conditional queries + reference_points_input = reference_boxes.unsqueeze(2) + query_sine_embed = self.position_encoding.encode_boxes(reference_points_input[:, :, 0, :]) + query_pos = self.ref_point_head(query_sine_embed) + + # Compute box relative position bias (RPB) attention mask + vision_cross_attn_mask = None + if spatial_shapes is not None and spatial_shapes.shape[0] == 1: + spatial_shape = (spatial_shapes[0, 0], spatial_shapes[0, 1]) + rpb_matrix = self._get_rpb_matrix(reference_boxes, spatial_shape) + # Prepend zeros row for presence token (it attends to all vision tokens equally) + vision_cross_attn_mask = F.pad(rpb_matrix, (0, 0, 1, 0), mode="constant", value=0) + + hidden_states = layer( + hidden_states, + query_pos=query_pos, + text_features=text_features, + vision_features=vision_features, + vision_pos_encoding=vision_pos_encoding, + text_cross_attn_mask=text_cross_attn_mask, + vision_cross_attn_mask=vision_cross_attn_mask, + **kwargs, + ) + + # Extract query hidden states (without presence token) for box refinement + query_hidden_states = hidden_states[:, 1:] + + # Box refinement: predict delta and update reference boxes + reference_boxes_before_sigmoid = inverse_sigmoid(reference_boxes) + delta_boxes = self.box_head(self.output_layer_norm(query_hidden_states)) + new_reference_boxes = (delta_boxes + reference_boxes_before_sigmoid).sigmoid() + reference_boxes = new_reference_boxes.detach() + + intermediate_outputs.append(self.output_layer_norm(query_hidden_states)) + intermediate_boxes.append(new_reference_boxes) + + # Process presence token + presence_hidden = hidden_states[:, :1] + presence_logits = self.presence_head(self.presence_layer_norm(presence_hidden)).squeeze(-1) + presence_logits = presence_logits.clamp( + min=-self.clamp_presence_logit_max_val, max=self.clamp_presence_logit_max_val + ) + intermediate_presence_logits.append(presence_logits) + + # Stack outputs from all layers + intermediate_outputs = torch.stack(intermediate_outputs) + intermediate_boxes = torch.stack(intermediate_boxes[:-1]) + intermediate_presence_logits = torch.stack(intermediate_presence_logits) + + return Sam3DETRDecoderOutput( + intermediate_hidden_states=intermediate_outputs, + reference_boxes=intermediate_boxes, + presence_logits=intermediate_presence_logits, + ) + + +class Sam3DotProductScoring(nn.Module): + """ + Computes classification scores by computing dot product between projected decoder queries and pooled text features. + This is used to determine confidence/presence scores for each query. + """ + + def __init__(self, config: Sam3Config): + super().__init__() + self.config = config + hidden_size = config.detr_decoder_config.hidden_size + projection_dim = config.detr_decoder_config.hidden_size + + self.text_mlp = Sam3DecoderMLP( + input_dim=hidden_size, + hidden_dim=config.detr_decoder_config.intermediate_size, + output_dim=hidden_size, + num_layers=2, + ) + self.text_mlp_dropout = nn.Dropout(config.detr_decoder_config.dropout) + self.text_mlp_out_norm = nn.LayerNorm(hidden_size) + + # Projections for text and query features + self.text_proj = nn.Linear(hidden_size, projection_dim) + self.query_proj = nn.Linear(hidden_size, projection_dim) + + # Scale factor for dot product + self.scale = float(1.0 / np.sqrt(projection_dim)) + + # Clamping to avoid numerical issues + self.clamp_logits = True + self.clamp_max_val = 12.0 + + def _pool_text_features(self, text_features: torch.Tensor, text_mask: torch.Tensor | None) -> torch.Tensor: + """ + Mean pool text features, accounting for padding. + + Args: + text_features: [batch_size, seq_len, hidden_size] + text_mask: [batch_size, seq_len] where True indicates valid tokens, False indicates padding + + Returns: + pooled_text: [batch_size, hidden_size] + """ + if text_mask is None: + # No padding, simple mean + return text_features.mean(dim=1) + + is_valid = text_mask.to(text_features.dtype).unsqueeze(-1) # [batch_size, seq_len, 1] + + # Count valid tokens per batch + num_valid = is_valid.sum(dim=1).clamp(min=1.0) # [batch_size, 1] + + # Mean pool only over valid tokens + pooled_text = (text_features * is_valid).sum(dim=1) / num_valid # [batch_size, hidden_size] + + return pooled_text + + def forward( + self, + decoder_hidden_states: torch.Tensor, + text_features: torch.Tensor, + text_mask: torch.Tensor | None = None, + ) -> torch.Tensor: + """ + Compute classification scores via dot product. + + Args: + decoder_hidden_states: [num_layers, batch_size, num_queries, hidden_size] + text_features: [batch_size, seq_len, hidden_size] + text_mask: [batch_size, seq_len] where True=valid, False=padding + + Returns: + scores: [num_layers, batch_size, num_queries, 1] + """ + orig_text_features = text_features + text_features = self.text_mlp(text_features) + text_features = self.text_mlp_dropout(text_features) + text_features = text_features + orig_text_features + text_features = self.text_mlp_out_norm(text_features) + + pooled_text = self._pool_text_features(text_features, text_mask) + + proj_text = self.text_proj(pooled_text) + proj_queries = self.query_proj(decoder_hidden_states) + + proj_text = proj_text.unsqueeze(-1) + scores = torch.matmul(proj_queries, proj_text.unsqueeze(0)) + scores = scores * self.scale + if self.clamp_logits: + scores = scores.clamp(min=-self.clamp_max_val, max=self.clamp_max_val) + + return scores + + +class Sam3MaskEmbedder(nn.Module): + """ + MLP that embeds object queries for mask prediction. + Similar to MaskFormer's mask embedder. + """ + + def __init__(self, config: Sam3MaskDecoderConfig): + super().__init__() + self.config = config + hidden_size = config.hidden_size + + self.layers = nn.ModuleList( + [ + nn.Linear(hidden_size, hidden_size), + nn.Linear(hidden_size, hidden_size), + nn.Linear(hidden_size, hidden_size), + ] + ) + self.activation = nn.ReLU() + + def forward(self, queries: torch.Tensor) -> torch.Tensor: + """ + Args: + queries: Query embeddings [batch_size, num_queries, hidden_size] + + Returns: + Mask embeddings [batch_size, num_queries, hidden_size] + """ + hidden_states = queries + for i, layer in enumerate(self.layers): + hidden_states = layer(hidden_states) + if i < len(self.layers) - 1: + hidden_states = self.activation(hidden_states) + return hidden_states + + +class Sam3PixelDecoder(nn.Module): + """ + Feature Pyramid Network (FPN) decoder that generates pixel-level features. + Inspired by MaskFormer's pixel decoder. + """ + + def __init__(self, config: Sam3MaskDecoderConfig): + super().__init__() + self.config = config + hidden_size = config.hidden_size + num_upsampling_stages = config.num_upsampling_stages + + # Create conv layers and norms for FPN + self.conv_layers = nn.ModuleList( + [ + nn.Conv2d(hidden_size, hidden_size, kernel_size=3, stride=1, padding=1) + for _ in range(num_upsampling_stages) + ] + ) + self.norms = nn.ModuleList([nn.GroupNorm(8, hidden_size) for _ in range(num_upsampling_stages)]) + + self.out_channels = hidden_size + + def forward(self, backbone_features: list[torch.Tensor]) -> torch.Tensor: + """ + Args: + backbone_features: List of backbone features [batch_size, hidden_size, H_i, W_i] + from low to high resolution (assumes already projected to hidden_size) + + Returns: + Pixel embeddings [batch_size, hidden_size, H, W] at the finest resolution + """ + # Start from the coarsest feature (last in list) + prev_fpn = backbone_features[-1] + # Iterate through features from coarse to fine (excluding the last which we started with) + for layer_idx, backbone_feat in enumerate(reversed(backbone_features[:-1])): + # Upsample previous FPN output to match current backbone feature size + prev_fpn = F.interpolate(prev_fpn, size=backbone_feat.shape[-2:], mode="nearest") + + # Add skip connection + prev_fpn = prev_fpn + backbone_feat + + # Apply conv and norm + prev_fpn = self.conv_layers[layer_idx](prev_fpn) + prev_fpn = self.norms[layer_idx](prev_fpn) + prev_fpn = F.relu(prev_fpn) + + return prev_fpn + + +class Sam3MaskDecoder(Sam3PreTrainedModel): + """ + Mask decoder that combines object queries with pixel-level features to predict instance masks. + Also produces a semantic segmentation output and supports cross-attention to prompts. + """ + + _can_record_outputs = { + "attentions": Sam3Attention, + } + + def __init__(self, config: Sam3MaskDecoderConfig): + super().__init__(config) + self.config = config + hidden_size = config.hidden_size + + # Pixel decoder (FPN) + self.pixel_decoder = Sam3PixelDecoder(config) + + # Mask embedder (MLP to transform queries) + self.mask_embedder = Sam3MaskEmbedder(config) + + # Projection from pixel decoder output to mask embedding space + self.instance_projection = nn.Conv2d(self.pixel_decoder.out_channels, hidden_size, kernel_size=1) + + # Semantic segmentation head (always present in UniversalSegmentationHead) + self.semantic_projection = nn.Conv2d(self.pixel_decoder.out_channels, 1, kernel_size=1) + + self.prompt_cross_attn = Sam3Attention(config) + self.prompt_cross_attn_norm = nn.LayerNorm(hidden_size) + self.prompt_cross_attn_dropout = nn.Dropout(config.dropout) + + self.post_init() + + @merge_with_config_defaults + @capture_outputs + def forward( + self, + decoder_queries: torch.Tensor, + backbone_features: list[torch.Tensor], + encoder_hidden_states: torch.Tensor, + prompt_features: torch.Tensor | None = None, + prompt_mask: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple | Sam3MaskDecoderOutput: + """ + Args: + decoder_queries: Decoder output queries [batch_size, num_queries, hidden_size] + backbone_features: List of backbone features to process through FPN + encoder_hidden_states: Encoder outputs [batch_size, seq_len, hidden_size] + prompt_features: Prompt features (text + geometry) for cross-attention [batch_size, prompt_len, hidden_size] + prompt_mask: Padding mask [batch_size, prompt_len] where True=valid, False=padding + + Returns: + Sam3MaskDecoderOutput containing predicted masks and semantic segmentation. + """ + if prompt_features is not None: + # Cross-attention: encoder features attend to prompt features + residual = encoder_hidden_states + normed_hidden_states = self.prompt_cross_attn_norm(encoder_hidden_states) + + cross_attn_mask = None + if prompt_mask is not None: + cross_attn_mask = create_bidirectional_mask( + config=self.config, + inputs_embeds=normed_hidden_states, + encoder_hidden_states=prompt_features, + attention_mask=prompt_mask, + ) + + attn_output, _ = self.prompt_cross_attn( + query=normed_hidden_states, + key=prompt_features, + value=prompt_features, + attention_mask=cross_attn_mask, + **kwargs, + ) + encoder_hidden_states = residual + self.prompt_cross_attn_dropout(attn_output) + + # Process backbone features through FPN to get pixel embeddings + pixel_embed = self._embed_pixels( + backbone_features=backbone_features, + encoder_hidden_states=encoder_hidden_states, + ) + + # Predict instance masks via dot product between query embeddings and pixel embeddings + instance_embeds = self.instance_projection(pixel_embed) + mask_embeddings = self.mask_embedder(decoder_queries) + pred_masks = torch.einsum("bqc,bchw->bqhw", mask_embeddings, instance_embeds) + + # Generate semantic segmentation + semantic_seg = self.semantic_projection(pixel_embed) + + return Sam3MaskDecoderOutput( + pred_masks=pred_masks, + semantic_seg=semantic_seg, + ) + + def _embed_pixels( + self, + backbone_features: list[torch.Tensor], + encoder_hidden_states: torch.Tensor, + ) -> torch.Tensor: + """ + Embed pixels by combining backbone FPN features with encoder vision features. + The encoder vision features replace the finest-resolution backbone feature. + + Args: + backbone_features: List of backbone features [batch_size, C, H_i, W_i] + encoder_hidden_states: Encoder outputs [batch_size, seq_len, hidden_size] + + Returns: + Pixel embeddings [batch_size, hidden_size, H, W] + """ + backbone_visual_feats = [feat.clone() for feat in backbone_features] + + # Extract vision features from encoder output and reshape to spatial format + spatial_dim = backbone_features[-1].shape[-2] * backbone_features[-1].shape[-1] + encoder_visual_embed = encoder_hidden_states[:, :spatial_dim, :] + batch_size, _, hidden_size = encoder_visual_embed.shape + height, width = backbone_features[-1].shape[-2:] + encoder_visual_embed = encoder_visual_embed.transpose(1, 2).reshape(batch_size, hidden_size, height, width) + + # Replace finest backbone feature with encoder vision features + backbone_visual_feats[-1] = encoder_visual_embed + + # Process through FPN decoder + pixel_embed = self.pixel_decoder(backbone_visual_feats) + + return pixel_embed + + +class Sam3Model(Sam3PreTrainedModel): + input_modalities = ["image", "text"] + _checkpoint_conversion_mapping = { + r"detector_model.(.+)": r"\1" # the regex allows to remove the prefix, and add it back in revert mode + } + _keys_to_ignore_on_load_unexpected = [ + r"^tracker_model.", + r"^tracker_neck.", + ] + + def __init__(self, config: Sam3Config): + # loading from a sam3_video config + if hasattr(config, "detector_config") and config.detector_config is not None: + detector_config = config.detector_config + if isinstance(detector_config, dict): + detector_config = Sam3Config(**detector_config) + config = detector_config + super().__init__(config) + self.vision_encoder = Sam3VisionModel(config.vision_config) + self.text_encoder = CLIPTextModelWithProjection(config.text_config) + self.vocab_size = config.text_config.vocab_size + + # Project text features from text encoder hidden size to model hidden size + # CLIP text encoder outputs 1024-dim features, but we need 256-dim for DETR + self.text_projection = nn.Linear(config.text_config.hidden_size, config.detr_encoder_config.hidden_size) + + # Pass _attn_implementation to subconfigs BEFORE creating modules + config.geometry_encoder_config._attn_implementation = config._attn_implementation + config.detr_encoder_config._attn_implementation = config._attn_implementation + config.detr_decoder_config._attn_implementation = config._attn_implementation + config.mask_decoder_config._attn_implementation = config._attn_implementation + + self.geometry_encoder = Sam3GeometryEncoder(config.geometry_encoder_config) + self.detr_encoder = Sam3DetrEncoder(config.detr_encoder_config) + self.detr_decoder = Sam3DetrDecoder(config.detr_decoder_config) + self.mask_decoder = Sam3MaskDecoder(config.mask_decoder_config) + + # Dot product scoring to compute classification scores + self.dot_product_scoring = Sam3DotProductScoring(config) + + self.post_init() + + @can_return_tuple + @auto_docstring + def get_text_features( + self, + input_ids: torch.LongTensor, + attention_mask: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple | BaseModelOutputWithPooling: + r""" + Example: + + ```python + >>> from transformers import Sam3Model, Sam3Processor + >>> from PIL import Image + >>> import httpx + >>> from io import BytesIO + + >>> model = Sam3Model.from_pretrained("facebook/sam3") + >>> processor = Sam3Processor.from_pretrained("facebook/sam3") + + >>> # Pre-compute text embeddings + >>> text_inputs = processor(text="cat", return_tensors="pt") + >>> text_embeds = model.get_text_features(**text_inputs).pooler_output + + >>> # Reuse text embeddings for multiple images + >>> url = "http://images.cocodataset.org/val2017/000000077595.jpg" + >>> with httpx.stream("GET", url) as response: + ... image = Image.open(BytesIO(response.read())) + >>> img_inputs = processor(images=image, return_tensors="pt") + >>> outputs = model(pixel_values=img_inputs.pixel_values, text_embeds=text_embeds) + ``` + """ + text_outputs = self.text_encoder( + input_ids=input_ids, attention_mask=attention_mask, return_dict=True, **kwargs + ) + last_hidden_state = text_outputs.last_hidden_state + text_outputs.pooler_output = self.text_projection(last_hidden_state) + + return text_outputs + + @auto_docstring + def get_vision_features( + self, + pixel_values: torch.FloatTensor, + **kwargs: Unpack[TransformersKwargs], + ) -> Sam3VisionEncoderOutput: + r""" + Example: + + ```python + >>> from transformers import Sam3Model, Sam3Processor + >>> from PIL import Image + >>> import httpx + >>> from io import BytesIO + + >>> model = Sam3Model.from_pretrained("facebook/sam3") + >>> processor = Sam3Processor.from_pretrained("facebook/sam3") + + >>> # Pre-compute vision embeddings + >>> url = "http://images.cocodataset.org/val2017/000000077595.jpg" + >>> with httpx.stream("GET", url) as response: + ... image = Image.open(BytesIO(response.read())) + >>> img_inputs = processor(images=image, return_tensors="pt") + >>> vision_embeds = model.get_vision_features(pixel_values=img_inputs.pixel_values) + + >>> # Reuse vision embeddings for multiple text prompts + >>> text_inputs = processor(text="cat", return_tensors="pt") + >>> outputs = model(vision_embeds=vision_embeds, input_ids=text_inputs.input_ids) + ``` + """ + vision_outputs = self.vision_encoder(pixel_values, **kwargs) + return vision_outputs + + @can_return_tuple + @auto_docstring + def forward( + self, + pixel_values: torch.FloatTensor | None = None, + vision_embeds: Sam3VisionEncoderOutput | None = None, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.Tensor | None = None, + text_embeds: torch.FloatTensor | None = None, + input_boxes: torch.FloatTensor | None = None, + input_boxes_labels: torch.LongTensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> Sam3ImageSegmentationOutput: + r""" + vision_embeds (`Sam3VisionEncoderOutput`, *optional*): + Pre-computed vision embeddings. Can be used to easily reuse vision embeddings. If provided, `pixel_values` + should not be passed. Mutually exclusive with `pixel_values`. + text_embeds (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*): + Pre-computed text embeddings. Can be used to easily reuse text embeddings. If provided, `input_ids` + should not be passed. Mutually exclusive with `input_ids`. + input_boxes (`torch.FloatTensor` of shape `(batch_size, num_boxes, 4)`, *optional*): + Normalized box coordinates in [0, 1] range, in (cx, cy, w, h) format. + input_boxes_labels (`torch.LongTensor` of shape `(batch_size, num_boxes)`, *optional*): + Labels for boxes: 1 (positive), 0 (negative). + + Example: + + ```python + >>> from PIL import Image + >>> import httpx + >>> from io import BytesIO + >>> from transformers import AutoModel, AutoProcessor + + >>> model = AutoModel.from_pretrained("facebook/sam3") + >>> processor = AutoProcessor.from_pretrained("facebook/sam3") + + >>> url = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/model_doc/sam-car.png" + >>> with httpx.stream("GET", url) as response: + ... image = Image.open(BytesIO(response.read())).convert("RGB") + >>> text = "car" + >>> inputs = processor(images=image, text=text, return_tensors="pt") + + >>> # Get segmentation output + >>> outputs = model(**inputs) + >>> pred_masks = outputs.pred_masks + >>> pred_boxes = outputs.pred_boxes + ``` + """ + if (pixel_values is None) == (vision_embeds is None): + raise ValueError("You must specify exactly one of pixel_values or vision_embeds") + + if (input_ids is None) == (text_embeds is None): + raise ValueError("You must specify exactly one of input_ids or text_embeds") + + if pixel_values is not None: + batch_size = pixel_values.shape[0] + device = pixel_values.device + else: + batch_size = vision_embeds.fpn_hidden_states[0].shape[0] + device = vision_embeds.fpn_hidden_states[0].device + + if vision_embeds is None: + vision_outputs = self.vision_encoder(pixel_values, **kwargs) + else: + vision_outputs = vision_embeds + + fpn_hidden_states = vision_outputs.fpn_hidden_states[:-1] + fpn_position_encoding = vision_outputs.fpn_position_encoding[:-1] + + if text_embeds is None: + text_features = self.get_text_features( + input_ids=input_ids, attention_mask=attention_mask, return_dict=True + ).pooler_output + else: + text_features = text_embeds + + text_mask = attention_mask.bool() if attention_mask is not None else None + has_geometry_prompts = input_boxes is not None and input_boxes.numel() > 0 + + geometry_prompt_features = None + geometry_prompt_mask = None + + if has_geometry_prompts: + if input_boxes is not None and input_boxes.numel() > 0: + box_embeddings = input_boxes # [batch_size, num_boxes, 4] + box_labels = ( + input_boxes_labels + if input_boxes_labels is not None + else torch.ones_like(box_embeddings[..., 0], dtype=torch.long) + ) + box_mask = ( + (input_boxes_labels != -10) + if input_boxes_labels is not None + else torch.ones(batch_size, input_boxes.shape[1], dtype=torch.bool, device=device) + ) + box_labels = torch.where(box_labels == -10, 0, box_labels) + else: + box_embeddings = torch.zeros(batch_size, 0, 4, dtype=text_features.dtype, device=device) + box_labels = torch.zeros(batch_size, 0, dtype=torch.long, device=device) + box_mask = torch.zeros(batch_size, 0, dtype=torch.bool, device=device) + + geometry_outputs = self.geometry_encoder( + box_embeddings=box_embeddings, + box_mask=box_mask, + box_labels=box_labels, + img_feats=fpn_hidden_states, + img_pos_embeds=fpn_position_encoding, + ) + + geometry_prompt_features = geometry_outputs.last_hidden_state + geometry_prompt_mask = geometry_outputs.attention_mask + + if geometry_prompt_features is not None: + # Repeat text_features for all geometry prompts + if text_features.shape[0] == 1 and geometry_prompt_features.shape[0] > 1: + text_features = text_features.repeat(geometry_prompt_features.shape[0], 1, 1) + combined_prompt_features = torch.cat([text_features, geometry_prompt_features], dim=1) + if text_mask is not None and text_mask.shape[0] == 1 and geometry_prompt_mask.shape[0] > 1: + text_mask = text_mask.repeat(geometry_prompt_mask.shape[0], 1) + + if text_mask is not None and geometry_prompt_mask is not None: + combined_prompt_mask = torch.cat([text_mask, geometry_prompt_mask], dim=1) + elif text_mask is not None: + geo_valid_mask = torch.ones( + batch_size, geometry_prompt_features.shape[1], dtype=torch.bool, device=device + ) + combined_prompt_mask = torch.cat([text_mask, geo_valid_mask], dim=1) + elif geometry_prompt_mask is not None: + text_valid_mask = torch.ones(batch_size, text_features.shape[1], dtype=torch.bool, device=device) + combined_prompt_mask = torch.cat([text_valid_mask, geometry_prompt_mask], dim=1) + else: + combined_prompt_mask = None + else: + combined_prompt_features = text_features + combined_prompt_mask = text_mask + + encoder_outputs = self.detr_encoder( + vision_features=[fpn_hidden_states[-1]], + text_features=combined_prompt_features, + vision_pos_embeds=[fpn_position_encoding[-1]], + text_mask=combined_prompt_mask, + **kwargs, + ) + + decoder_outputs = self.detr_decoder( + vision_features=encoder_outputs.last_hidden_state, + text_features=encoder_outputs.text_features, + vision_pos_encoding=encoder_outputs.pos_embeds_flattened, + text_mask=combined_prompt_mask, + spatial_shapes=encoder_outputs.spatial_shapes, + **kwargs, + ) + + # Refine boxes from decoder + all_box_offsets = self.detr_decoder.box_head(decoder_outputs.intermediate_hidden_states) + reference_boxes_inv_sig = inverse_sigmoid(decoder_outputs.reference_boxes) + all_pred_boxes_cxcywh = (reference_boxes_inv_sig + all_box_offsets).sigmoid() + all_pred_boxes = box_cxcywh_to_xyxy(all_pred_boxes_cxcywh) + + all_pred_logits = self.dot_product_scoring( + decoder_hidden_states=decoder_outputs.intermediate_hidden_states, + text_features=encoder_outputs.text_features, + text_mask=combined_prompt_mask, + ).squeeze(-1) + + pred_logits = all_pred_logits[-1] + pred_boxes = all_pred_boxes[-1] + decoder_hidden_states = decoder_outputs.intermediate_hidden_states[-1] + presence_logits = decoder_outputs.presence_logits[-1] + + mask_outputs = self.mask_decoder( + decoder_queries=decoder_hidden_states, + backbone_features=list(fpn_hidden_states), + encoder_hidden_states=encoder_outputs.last_hidden_state, + prompt_features=combined_prompt_features, + prompt_mask=combined_prompt_mask, + **kwargs, + ) + + return Sam3ImageSegmentationOutput( + pred_masks=mask_outputs.pred_masks, + pred_boxes=pred_boxes, + pred_logits=pred_logits, + presence_logits=presence_logits, + semantic_seg=mask_outputs.semantic_seg, + decoder_hidden_states=decoder_outputs.hidden_states, + decoder_reference_boxes=decoder_outputs.reference_boxes, + encoder_hidden_states=encoder_outputs.hidden_states, + vision_hidden_states=vision_outputs.hidden_states, + vision_attentions=vision_outputs.attentions, + detr_encoder_attentions=encoder_outputs.attentions, + detr_decoder_attentions=decoder_outputs.attentions, + mask_decoder_attentions=mask_outputs.attentions, + ) + + +__all__ = ["Sam3Model", "Sam3VisionModel", "Sam3ViTModel", "Sam3PreTrainedModel"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam3/modular_sam3.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam3/modular_sam3.py new file mode 100644 index 0000000000000000000000000000000000000000..591a193ab3f463d06706d3c232f369d296f7ff8a --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam3/modular_sam3.py @@ -0,0 +1,252 @@ +# Copyright 2025 The Meta AI Authors and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + + +import torch + +from ...image_utils import ( + IMAGENET_STANDARD_MEAN, + IMAGENET_STANDARD_STD, +) +from ..sam2.image_processing_sam2_fast import Sam2ImageProcessorFast + + +def _scale_boxes(boxes, target_sizes): + """ + Scale batch of bounding boxes to the target sizes. + + Args: + boxes (`torch.Tensor` of shape `(batch_size, num_boxes, 4)`): + Bounding boxes to scale. Each box is expected to be in (x1, y1, x2, y2) format. + target_sizes (`list[tuple[int, int]]` or `torch.Tensor` of shape `(batch_size, 2)`): + Target sizes to scale the boxes to. Each target size is expected to be in (height, width) format. + + Returns: + `torch.Tensor` of shape `(batch_size, num_boxes, 4)`: Scaled bounding boxes. + """ + + if isinstance(target_sizes, (list, tuple)): + image_height = torch.tensor([i[0] for i in target_sizes]) + image_width = torch.tensor([i[1] for i in target_sizes]) + elif isinstance(target_sizes, torch.Tensor): + image_height, image_width = target_sizes.unbind(1) + else: + raise TypeError("`target_sizes` must be a list, tuple or torch.Tensor") + + scale_factor = torch.stack([image_width, image_height, image_width, image_height], dim=1) + scale_factor = scale_factor.unsqueeze(1).to(boxes.device) + boxes = boxes * scale_factor + return boxes + + +class Sam3ImageProcessorFast(Sam2ImageProcessorFast): + image_mean = IMAGENET_STANDARD_MEAN + image_std = IMAGENET_STANDARD_STD + size = {"height": 1008, "width": 1008} + mask_size = {"height": 288, "width": 288} + + def post_process_semantic_segmentation( + self, outputs, target_sizes: list[tuple] | None = None, threshold: float = 0.5 + ): + """ + Converts the output of [`Sam3Model`] into semantic segmentation maps. + + Args: + outputs ([`Sam3ImageSegmentationOutput`]): + Raw outputs of the model containing semantic_seg. + target_sizes (`list[tuple]` of length `batch_size`, *optional*): + List of tuples corresponding to the requested final size (height, width) of each prediction. If unset, + predictions will not be resized. + threshold (`float`, *optional*, defaults to 0.5): + Threshold for binarizing the semantic segmentation masks. + + Returns: + semantic_segmentation: `list[torch.Tensor]` of length `batch_size`, where each item is a semantic + segmentation map of shape (height, width) corresponding to the target_sizes entry (if `target_sizes` is + specified). Each entry is a binary mask (0 or 1). + """ + # Get semantic segmentation output + # semantic_seg has shape (batch_size, 1, height, width) + semantic_logits = outputs.semantic_seg + + if semantic_logits is None: + raise ValueError( + "Semantic segmentation output is not available in the model outputs. " + "Make sure the model was run with semantic segmentation enabled." + ) + + # Apply sigmoid to convert logits to probabilities + semantic_probs = semantic_logits.sigmoid() + + # Resize and binarize semantic segmentation maps + if target_sizes is not None: + if len(semantic_logits) != len(target_sizes): + raise ValueError( + "Make sure that you pass in as many target sizes as the batch dimension of the logits" + ) + + semantic_segmentation = [] + + for idx in range(len(semantic_logits)): + resized_probs = torch.nn.functional.interpolate( + semantic_probs[idx].unsqueeze(dim=0), + size=target_sizes[idx], + mode="bilinear", + align_corners=False, + ) + # Binarize: values > threshold become 1, otherwise 0 + semantic_map = (resized_probs[0, 0] > threshold).to(torch.long) + semantic_segmentation.append(semantic_map) + else: + # Binarize without resizing + semantic_segmentation = (semantic_probs[:, 0] > threshold).to(torch.long) + semantic_segmentation = [semantic_segmentation[i] for i in range(semantic_segmentation.shape[0])] + + return semantic_segmentation + + def post_process_object_detection(self, outputs, threshold: float = 0.3, target_sizes: list[tuple] | None = None): + """ + Converts the raw output of [`Sam3Model`] into final bounding boxes in (top_left_x, top_left_y, + bottom_right_x, bottom_right_y) format. + + Args: + outputs ([`Sam3ImageSegmentationOutput`]): + Raw outputs of the model containing pred_boxes, pred_logits, and optionally presence_logits. + threshold (`float`, *optional*, defaults to 0.3): + Score threshold to keep object detection predictions. + target_sizes (`list[tuple[int, int]]`, *optional*): + List of tuples (`tuple[int, int]`) containing the target size `(height, width)` of each image in the + batch. If unset, predictions will not be resized. + + Returns: + `list[dict]`: A list of dictionaries, each dictionary containing the following keys: + - **scores** (`torch.Tensor`): The confidence scores for each predicted box on the image. + - **boxes** (`torch.Tensor`): Image bounding boxes in (top_left_x, top_left_y, bottom_right_x, + bottom_right_y) format. + """ + pred_logits = outputs.pred_logits # (batch_size, num_queries) + pred_boxes = outputs.pred_boxes # (batch_size, num_queries, 4) in xyxy format + presence_logits = outputs.presence_logits # (batch_size, 1) or None + + batch_size = pred_logits.shape[0] + + if target_sizes is not None and len(target_sizes) != batch_size: + raise ValueError("Make sure that you pass in as many target sizes as images") + + # Compute scores: combine pred_logits with presence_logits if available + batch_scores = pred_logits.sigmoid() + if presence_logits is not None: + presence_scores = presence_logits.sigmoid() # (batch_size, 1) + batch_scores = batch_scores * presence_scores # Broadcast multiplication + + # Boxes are already in xyxy format from the model + batch_boxes = pred_boxes + + # Convert from relative [0, 1] to absolute [0, height/width] coordinates + if target_sizes is not None: + batch_boxes = _scale_boxes(batch_boxes, target_sizes) + + results = [] + for scores, boxes in zip(batch_scores, batch_boxes): + keep = scores > threshold + scores = scores[keep] + boxes = boxes[keep] + results.append({"scores": scores, "boxes": boxes}) + + return results + + def post_process_instance_segmentation( + self, + outputs, + threshold: float = 0.3, + mask_threshold: float = 0.5, + target_sizes: list[tuple] | None = None, + ): + """ + Converts the raw output of [`Sam3Model`] into instance segmentation predictions with bounding boxes and masks. + + Args: + outputs ([`Sam3ImageSegmentationOutput`]): + Raw outputs of the model containing pred_boxes, pred_logits, pred_masks, and optionally + presence_logits. + threshold (`float`, *optional*, defaults to 0.3): + Score threshold to keep instance predictions. + mask_threshold (`float`, *optional*, defaults to 0.5): + Threshold for binarizing the predicted masks. + target_sizes (`list[tuple[int, int]]`, *optional*): + List of tuples (`tuple[int, int]`) containing the target size `(height, width)` of each image in the + batch. If unset, predictions will not be resized. + + Returns: + `list[dict]`: A list of dictionaries, each dictionary containing the following keys: + - **scores** (`torch.Tensor`): The confidence scores for each predicted instance on the image. + - **boxes** (`torch.Tensor`): Image bounding boxes in (top_left_x, top_left_y, bottom_right_x, + bottom_right_y) format. + - **masks** (`torch.Tensor`): Binary segmentation masks for each instance, shape (num_instances, + height, width). + """ + pred_logits = outputs.pred_logits # (batch_size, num_queries) + pred_boxes = outputs.pred_boxes # (batch_size, num_queries, 4) in xyxy format + pred_masks = outputs.pred_masks # (batch_size, num_queries, height, width) + presence_logits = outputs.presence_logits # (batch_size, 1) or None + + batch_size = pred_logits.shape[0] + + if target_sizes is not None and len(target_sizes) != batch_size: + raise ValueError("Make sure that you pass in as many target sizes as images") + + # Compute scores: combine pred_logits with presence_logits if available + batch_scores = pred_logits.sigmoid() + if presence_logits is not None: + presence_scores = presence_logits.sigmoid() # (batch_size, 1) + batch_scores = batch_scores * presence_scores # Broadcast multiplication + + # Apply sigmoid to mask logits + batch_masks = pred_masks.sigmoid() + + # Boxes are already in xyxy format from the model + batch_boxes = pred_boxes + + # Scale boxes to target sizes if provided + if target_sizes is not None: + batch_boxes = _scale_boxes(batch_boxes, target_sizes) + + results = [] + for idx, (scores, boxes, masks) in enumerate(zip(batch_scores, batch_boxes, batch_masks)): + # Filter by score threshold + keep = scores > threshold + scores = scores[keep] + boxes = boxes[keep] + masks = masks[keep] # (num_keep, height, width) + + # Resize masks to target size if provided + if target_sizes is not None: + target_size = target_sizes[idx] + if len(masks) > 0: + masks = torch.nn.functional.interpolate( + masks.unsqueeze(0), # (1, num_keep, height, width) + size=target_size, + mode="bilinear", + align_corners=False, + ).squeeze(0) # (num_keep, target_height, target_width) + + # Binarize masks + masks = (masks > mask_threshold).to(torch.long) + + results.append({"scores": scores, "boxes": boxes, "masks": masks}) + + return results + + +__all__ = ["Sam3ImageProcessorFast"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam3/processing_sam3.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam3/processing_sam3.py new file mode 100644 index 0000000000000000000000000000000000000000..201ddb54a49d076976e8ea1c82a8d5d076d0d6d0 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam3/processing_sam3.py @@ -0,0 +1,657 @@ +# Copyright 2025 The HuggingFace Inc. team. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +""" +Processor class for SAM3. +""" + +from copy import deepcopy + +import numpy as np + +from ...image_utils import ImageInput +from ...processing_utils import ProcessorMixin +from ...tokenization_utils_base import BatchEncoding, PreTokenizedInput, TextInput +from ...utils import TensorType, auto_docstring, is_torch_available, logging +from ...utils.import_utils import requires + + +logger = logging.get_logger(__name__) + +if is_torch_available(): + import torch + + +def box_cxcywh_to_xyxy(x): + x_c, y_c, w, h = x.unbind(-1) + b = [(x_c - 0.5 * w), (y_c - 0.5 * h), (x_c + 0.5 * w), (y_c + 0.5 * h)] + return torch.stack(b, dim=-1) + + +def box_cxcywh_to_xywh(x): + x_c, y_c, w, h = x.unbind(-1) + b = [(x_c - 0.5 * w), (y_c - 0.5 * h), (w), (h)] + return torch.stack(b, dim=-1) + + +def box_xywh_to_xyxy(x): + x, y, w, h = x.unbind(-1) + b = [(x), (y), (x + w), (y + h)] + return torch.stack(b, dim=-1) + + +def box_xywh_to_cxcywh(x): + x, y, w, h = x.unbind(-1) + b = [(x + 0.5 * w), (y + 0.5 * h), (w), (h)] + return torch.stack(b, dim=-1) + + +def box_xyxy_to_xywh(x): + x, y, X, Y = x.unbind(-1) + b = [(x), (y), (X - x), (Y - y)] + return torch.stack(b, dim=-1) + + +def box_xyxy_to_cxcywh(x): + x0, y0, x1, y1 = x.unbind(-1) + b = [(x0 + x1) / 2, (y0 + y1) / 2, (x1 - x0), (y1 - y0)] + return torch.stack(b, dim=-1) + + +def box_area(boxes): + """ + Batched version of box area. Boxes should be in [x0, y0, x1, y1] format. + + Inputs: + - boxes: Tensor of shape (..., 4) + + Returns: + - areas: Tensor of shape (...,) + """ + x0, y0, x1, y1 = boxes.unbind(-1) + return (x1 - x0) * (y1 - y0) + + +@requires(backends=("torch",)) +@auto_docstring +class Sam3Processor(ProcessorMixin): + def __init__( + self, image_processor, tokenizer, target_size: int | None = None, point_pad_value: int = -10, **kwargs + ): + r""" + target_size (`int`, *optional*): + The target size (target_size, target_size) to which the image will be resized. + point_pad_value (`int`, *optional*, defaults to -10): + The value used for padding input boxes. + """ + super().__init__(image_processor, tokenizer, **kwargs) + self.point_pad_value = point_pad_value + self.target_size = target_size if target_size is not None else self.image_processor.size["height"] + + @auto_docstring + def __call__( + self, + images: ImageInput | None = None, + text: TextInput | PreTokenizedInput | list[TextInput] | list[PreTokenizedInput] | None = None, + segmentation_maps: ImageInput | None = None, + input_boxes: list[list[list[float]]] | torch.Tensor | None = None, + input_boxes_labels: list[list[list[int]]] | torch.Tensor | None = None, + original_sizes: list[list[float]] | torch.Tensor | None = None, + return_tensors: str | TensorType | None = None, + **kwargs, + ) -> BatchEncoding: + r""" + images (`ImageInput`, *optional*): + The image(s) to process. + text (`str`, `list[str]`, `list[list[str]]`, *optional*): + The text to process. + segmentation_maps (`ImageInput`, *optional*): + The segmentation maps to process. + input_boxes (`list[list[list[float]]]`, `torch.Tensor`, *optional*): + The bounding boxes to process. + input_boxes_labels (`list[list[int]]`, `torch.Tensor`, *optional*): + The labels for the bounding boxes. + original_sizes (`list[list[float]]`, `torch.Tensor`, *optional*): + The original sizes of the images. + + Returns: + A [`BatchEncoding`] with the following fields: + - `pixel_values` (`torch.Tensor`): The processed image(s). + - `original_sizes` (`list[list[float]]`): The original sizes of the images. + - `labels` (`torch.Tensor`): The processed segmentation maps (if provided). + - `input_boxes_labels` (`torch.Tensor`): The processed labels for the bounding boxes. + - `input_boxes` (`torch.Tensor`): The processed bounding boxes. + """ + encoding = None + if images is not None: + encoding = self.image_processor( + images, + segmentation_maps=segmentation_maps, + return_tensors=return_tensors, + **kwargs, + ) + elif original_sizes is not None: + if isinstance(original_sizes, torch.Tensor): + original_sizes = original_sizes.cpu().tolist() + encoding = BatchEncoding({"original_sizes": original_sizes}, tensor_type=return_tensors) + elif input_boxes is not None: + raise ValueError("Either images or original_sizes must be provided if input_boxes is not None") + + text = self._resolve_text_prompts(text, input_boxes) + if text is not None: + text_inputs = self.tokenizer(text, return_tensors=return_tensors, padding="max_length", max_length=32) + if encoding is not None: + encoding.update(text_inputs) + else: + encoding = text_inputs + + # Process input boxes if provided + if input_boxes is not None: + original_sizes = encoding["original_sizes"] + # Validate and convert inputs to standardized format + processed_boxes = self._validate_single_input( + input_boxes, + expected_depth=3, + input_name="boxes", + expected_format="[image level, box level, box coordinates]", + expected_coord_size=4, + ) + processed_boxes_labels = self._validate_single_input( + input_boxes_labels, + expected_depth=2, + input_name="labels", + expected_format="[image level, box level]", + ) + + # Get padding requirements for all inputs + if processed_boxes is not None: + boxes_max_dims = self._get_nested_dimensions(processed_boxes)[:2] + if processed_boxes_labels is not None: + boxes_labels_max_dims = self._get_nested_dimensions(processed_boxes_labels)[:2] + + # Ensure boxes and labels have consistent dimensions + if processed_boxes is not None and processed_boxes_labels is not None: + if boxes_max_dims != boxes_labels_max_dims: + raise ValueError( + "Input boxes and labels have inconsistent dimensions. Please ensure they have the same dimensions." + ) + + # Pad and normalize all inputs to final tensor format + if processed_boxes is not None: + padded_boxes = self._pad_nested_list(processed_boxes, boxes_max_dims + [4]) + final_boxes = torch.tensor(padded_boxes, dtype=torch.float32) + self._normalize_tensor_coordinates( + final_boxes, original_sizes, is_bounding_box=True, preserve_padding=True + ) + final_boxes = box_xyxy_to_cxcywh(final_boxes) + encoding.update({"input_boxes": final_boxes}) + + if processed_boxes_labels is not None: + padded_boxes_labels = self._pad_nested_list(processed_boxes_labels, boxes_labels_max_dims) + final_boxes_labels = torch.tensor(padded_boxes_labels, dtype=torch.int64) + encoding.update({"input_boxes_labels": final_boxes_labels}) + + return encoding + + def _normalize_coordinates(self, coords: "torch.Tensor", original_size, is_bounding_box=False) -> "torch.Tensor": + """ + Expects a numpy array of length 2 in the final dimension. Requires the original image size in (H, W) format. + + Args: + target_size (`int`): + The target size of the image. + coords (`torch.Tensor`): + The coordinates to be normalized. + original_size (`tuple`): + The original size of the image. + is_bounding_box (`bool`, *optional*, defaults to `False`): + Whether the coordinates are bounding boxes. + """ + old_h, old_w = original_size + coords = deepcopy(coords).float() + + if is_bounding_box: + coords = coords.reshape(-1, 2, 2) + coords[..., 0] = coords[..., 0] / old_w + coords[..., 1] = coords[..., 1] / old_h + + if is_bounding_box: + coords = coords.reshape(-1, 4) + + return coords + + def _convert_to_nested_list(self, data, expected_depth, current_depth=0): + """ + Recursively convert various input formats (tensors, numpy arrays, lists) to nested lists. + Preserves None values within lists. + + Args: + data: Input data in any format (may be None or contain None values) + expected_depth: Expected nesting depth + current_depth: Current depth in recursion + + Returns: + Nested list representation of the data (or None) + """ + if data is None: + return None + + # Convert tensor/numpy to list if we're at a leaf level or if it's a multi-dimensional array + if isinstance(data, torch.Tensor): # PyTorch tensor + if current_depth == expected_depth - 2 or len(data.shape) <= 2: # At coordinate level or small tensor + return data.numpy().tolist() + else: + return [self._convert_to_nested_list(item, expected_depth, current_depth + 1) for item in data] + elif isinstance(data, np.ndarray): # NumPy array + if current_depth == expected_depth - 2 or len(data.shape) <= 2: # At coordinate level or small array + return data.tolist() + else: + return [self._convert_to_nested_list(item, expected_depth, current_depth + 1) for item in data] + elif isinstance(data, list): + if current_depth == expected_depth: + # We've reached the expected depth, return as is + return data + else: + # Continue recursion, preserving None values + return [ + self._convert_to_nested_list(item, expected_depth, current_depth + 1) if item is not None else None + for item in data + ] + elif isinstance(data, (int, float)): + return data + else: + raise ValueError(f"Unsupported data type: {type(data)}") + + def _resolve_text_prompts(self, text, input_boxes): + """ + Resolve text prompts by setting defaults based on prompt types. + """ + # If no text provided, infer default based on prompt type + if text is None: + return "visual" if input_boxes else None + + if not isinstance(text, (list, tuple)): + return text + + # Validate list/tuple length matches both prompt types if provided + text = list(text) # Convert to list to allow modification + + if input_boxes and len(text) != len(input_boxes): + raise ValueError( + f"The number of text prompts must match the number of input boxes. " + f"Got {len(text)} text prompts and {len(input_boxes)} input boxes." + ) + + # Fill in None values with defaults based on corresponding prompt + for i, text_value in enumerate(text): + if text_value is None and input_boxes and input_boxes[i] is not None: + text[i] = "visual" + + return text + + def _get_nested_dimensions(self, nested_list, max_dims=None): + """ + Get the maximum dimensions at each level of nesting, skipping None values. + + Args: + nested_list (`list`): + Nested list structure (may contain None values). + max_dims (`list`, *optional*): + Current maximum dimensions (for recursion). + + Returns: + `list`: A list of maximum dimensions for each nesting level. + """ + if max_dims is None: + max_dims = [] + + if not isinstance(nested_list, list): + return max_dims + + if len(max_dims) == 0: + max_dims.append(len(nested_list)) + else: + max_dims[0] = max(max_dims[0], len(nested_list)) + + if len(nested_list) > 0: + for item in nested_list: + # Skip None values + if item is None: + continue + if isinstance(item, list): + sub_dims = self._get_nested_dimensions(item) + # Merge sub_dims into max_dims + for i, dim in enumerate(sub_dims): + if i + 1 >= len(max_dims): + max_dims.append(dim) + else: + max_dims[i + 1] = max(max_dims[i + 1], dim) + + return max_dims + + def _pad_nested_list(self, nested_list, target_dims, current_level=0, pad_value=None): + """ + Recursively pad a nested list to match target dimensions. Replaces None values with padded structures. + + Args: + nested_list (`list`): + Nested list to pad (may contain None values). + target_dims (`list`): + Target dimensions for each level. + current_level (`int`, *optional*, defaults to 0): + Current nesting level. + pad_value (`int`, *optional*): + Value to use for padding. + + Returns: + `list`: The padded nested list. + """ + if pad_value is None: + pad_value = self.point_pad_value + + if current_level >= len(target_dims): + return nested_list + + # Ensure we have a list + if not isinstance(nested_list, list): + nested_list = [nested_list] + + # Pad current level + current_size = len(nested_list) + target_size = target_dims[current_level] + + # Pad with appropriate values + if current_level == len(target_dims) - 1: + # At the coordinate level, pad with pad_value + nested_list.extend([pad_value] * (target_size - current_size)) + else: + # At higher levels, pad with nested structures + if current_size > 0: + # Create appropriately sized template + if current_level < len(target_dims) - 2: + # For non-coordinate levels, create empty nested structure + template_dims = target_dims[current_level + 1 :] + template = self._create_empty_nested_structure(template_dims, pad_value) + else: + # For coordinate level, create list of pad_values + template = [pad_value] * target_dims[current_level + 1] + + nested_list.extend([deepcopy(template) for _ in range(target_size - current_size)]) + else: + # Create from scratch + template_dims = target_dims[current_level + 1 :] + template = self._create_empty_nested_structure(template_dims, pad_value) + nested_list.extend([deepcopy(template) for _ in range(target_size)]) + + # Recursively pad sublists, replacing None with padded structures + if current_level < len(target_dims) - 1: + for i in range(len(nested_list)): + if nested_list[i] is None: + # Replace None with fully padded structure + template_dims = target_dims[current_level + 1 :] + nested_list[i] = self._create_empty_nested_structure(template_dims, pad_value) + elif isinstance(nested_list[i], list): + nested_list[i] = self._pad_nested_list(nested_list[i], target_dims, current_level + 1, pad_value) + + return nested_list + + def _create_empty_nested_structure(self, dims, pad_value): + """ + Create an empty nested structure with given dimensions filled with pad_value. + + Args: + dims (`list`): + The dimensions of the nested structure. + pad_value (`int`): + The value to fill the structure with. + """ + if len(dims) == 1: + return [pad_value] * dims[0] + else: + return [self._create_empty_nested_structure(dims[1:], pad_value) for _ in range(dims[0])] + + def _get_nesting_level(self, input_list): + """ + Get the nesting level of a list structure, skipping None values. + + Args: + input_list (`list`): + The list to get the nesting level of. + """ + if isinstance(input_list, list): + if len(input_list) == 0: + return 1 + # Find first non-None element to determine nesting level + for item in input_list: + if item is not None: + return 1 + self._get_nesting_level(item) + # All elements are None, treat as single level + return 1 + elif isinstance(input_list, (np.ndarray, torch.Tensor)): + # For arrays/tensors, the nesting level is the number of dimensions + return len(input_list.shape) + return 0 + + def _validate_single_input( + self, + data: torch.Tensor | np.ndarray | list, + expected_depth: int, + input_name: str, + expected_format: str, + expected_coord_size: int | None = None, + ) -> list: + """ + Validate a single input by ensuring proper nesting and raising an error if the input is not valid. + + Args: + data (`torch.Tensor`, `np.ndarray`, or `list`): + Input data to process. + expected_depth (`int`): + Expected nesting depth. + input_name (`str`): + Name of the input for error messages. + expected_format (`str`): + The expected format of the input. + expected_coord_size (`int`, *optional*): + Expected coordinate size (4 for boxes, None for labels). + . + """ + if data is None: + return None + + # Handle tensors and numpy arrays first + if isinstance(data, (torch.Tensor, np.ndarray)): + # For tensors/arrays, we can directly check the number of dimensions + if data.ndim != expected_depth: + raise ValueError( + f"Input {input_name} must be a tensor/array with {expected_depth} dimensions. The expected nesting format is {expected_format}. Got {data.ndim} dimensions." + ) + elif expected_coord_size is not None: + if data.shape[-1] != expected_coord_size: + raise ValueError( + f"Input {input_name} must be a tensor/array with {expected_coord_size} as the last dimension, got {data.shape[-1]}." + ) + return self._convert_to_nested_list(data, expected_depth) + + # Handle nested lists + if isinstance(data, list): + current_depth = self._get_nesting_level(data) + if current_depth != expected_depth: + raise ValueError( + f"Input {input_name} must be a nested list with {expected_depth} levels. The expected nesting format is {expected_format}. Got {current_depth} levels." + ) + return self._convert_to_nested_list(data, expected_depth) + + def _normalize_tensor_coordinates(self, tensor, original_sizes, is_bounding_box=False, preserve_padding=False): + """ + Helper method to normalize coordinates in a tensor across multiple images. + + Args: + tensor (`torch.Tensor`): + Input tensor with coordinates. + original_sizes (`list`): + Original image sizes. + is_bounding_box (`bool`, *optional*, defaults to `False`): + Whether coordinates are bounding boxes. + preserve_padding (`bool`, *optional*, defaults to `False`): + Whether to preserve padding values (for boxes). + """ + if preserve_padding: + # For boxes: avoid normalizing pad values + mask = tensor != self.point_pad_value + coord_mask = mask.all(dim=-1, keepdim=True) + + for img_idx in range(len(original_sizes)): + if img_idx < tensor.shape[0]: + original_size = original_sizes[img_idx] if img_idx < len(original_sizes) else original_sizes[0] + normalized_coords = self._normalize_coordinates( + tensor[img_idx], original_size, is_bounding_box=is_bounding_box + ) + + if preserve_padding: + # Only update non-padded values + img_mask = coord_mask[img_idx] + tensor[img_idx] = torch.where( + img_mask.expand_as(tensor[img_idx]), normalized_coords, tensor[img_idx] + ) + else: + tensor[img_idx] = normalized_coords + + def post_process_semantic_segmentation(self, outputs, target_sizes=None, threshold=0.5): + """ + Converts the output of [`Sam3Model`] into semantic segmentation maps. + + Args: + outputs ([`Sam3ImageSegmentationOutput`]): + Raw outputs of the model containing semantic_seg. + target_sizes (`list[tuple]` of length `batch_size`, *optional*): + List of tuples corresponding to the requested final size (height, width) of each prediction. If unset, + predictions will not be resized. + threshold (`float`, *optional*, defaults to 0.5): + Threshold for binarizing the semantic segmentation masks. + + Returns: + semantic_segmentation: `list[torch.Tensor]` of length `batch_size`, where each item is a semantic + segmentation map of shape (height, width) corresponding to the target_sizes entry (if `target_sizes` is + specified). Each entry is a binary mask (0 or 1). + """ + return self.image_processor.post_process_semantic_segmentation(outputs, target_sizes, threshold) + + def post_process_object_detection(self, outputs, threshold=0.3, target_sizes=None): + """ + Converts the raw output of [`Sam3Model`] into final bounding boxes in (top_left_x, top_left_y, + bottom_right_x, bottom_right_y) format. This is a convenience wrapper around the image processor method. + + Args: + outputs ([`Sam3ImageSegmentationOutput`]): + Raw outputs of the model containing pred_boxes, pred_logits, and optionally presence_logits. + threshold (`float`, *optional*, defaults to 0.3): + Score threshold to keep object detection predictions. + target_sizes (`list[tuple[int, int]]`, *optional*): + List of tuples (`tuple[int, int]`) containing the target size `(height, width)` of each image in the + batch. If unset, predictions will not be resized. + + Returns: + `list[dict]`: A list of dictionaries, each dictionary containing the following keys: + - **scores** (`torch.Tensor`): The confidence scores for each predicted box on the image. + - **boxes** (`torch.Tensor`): Image bounding boxes in (top_left_x, top_left_y, bottom_right_x, + bottom_right_y) format. + + Example: + + ```python + >>> from transformers import AutoModel, AutoProcessor + >>> from PIL import Image + >>> import httpx + >>> from io import BytesIO + + >>> model = AutoModel.from_pretrained("facebook/sam3-base") + >>> processor = AutoProcessor.from_pretrained("facebook/sam3-base") + + >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg" + >>> with httpx.stream("GET", url) as response: + ... image = Image.open(BytesIO(response.read())) + >>> inputs = processor(images=image, text="cat", return_tensors="pt") + >>> outputs = model(**inputs) + + >>> # Post-process to get bounding boxes + >>> results = processor.post_process_object_detection(outputs, threshold=0.3, target_sizes=[image.size[::-1]]) + >>> boxes = results[0]["boxes"] + >>> scores = results[0]["scores"] + ``` + """ + return self.image_processor.post_process_object_detection(outputs, threshold, target_sizes) + + def post_process_instance_segmentation( + self, + outputs, + threshold=0.3, + mask_threshold=0.5, + target_sizes=None, + ): + """ + Converts the raw output of [`Sam3Model`] into instance segmentation predictions with bounding boxes and masks. + This is a convenience wrapper around the image processor method. + + Args: + outputs ([`Sam3ImageSegmentationOutput`]): + Raw outputs of the model containing pred_boxes, pred_logits, pred_masks, and optionally + presence_logits. + threshold (`float`, *optional*, defaults to 0.3): + Score threshold to keep instance predictions. + mask_threshold (`float`, *optional*, defaults to 0.5): + Threshold for binarizing the predicted masks. + target_sizes (`list[tuple[int, int]]`, *optional*): + List of tuples (`tuple[int, int]`) containing the target size `(height, width)` of each image in the + batch. If unset, predictions will not be resized. + + Returns: + `list[dict]`: A list of dictionaries, each dictionary containing the following keys: + - **scores** (`torch.Tensor`): The confidence scores for each predicted instance on the image. + - **boxes** (`torch.Tensor`): Image bounding boxes in (top_left_x, top_left_y, bottom_right_x, + bottom_right_y) format. + - **masks** (`torch.Tensor`): Binary segmentation masks for each instance, shape (num_instances, + height, width). + + Example: + + ```python + >>> from transformers import AutoModel, AutoProcessor + >>> from PIL import Image + >>> import httpx + >>> from io import BytesIO + + >>> model = AutoModel.from_pretrained("facebook/sam3-base") + >>> processor = AutoProcessor.from_pretrained("facebook/sam3-base") + + >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg" + >>> with httpx.stream("GET", url) as response: + ... image = Image.open(BytesIO(response.read())) + >>> inputs = processor(images=image, text="cat", return_tensors="pt") + >>> outputs = model(**inputs) + + >>> # Post-process to get instance segmentation + >>> results = processor.post_process_instance_segmentation( + ... outputs, threshold=0.3, target_sizes=[image.size[::-1]] + ... ) + >>> masks = results[0]["masks"] + >>> boxes = results[0]["boxes"] + >>> scores = results[0]["scores"] + ``` + """ + return self.image_processor.post_process_instance_segmentation( + outputs, threshold, mask_threshold, target_sizes + ) + + +__all__ = ["Sam3Processor"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam3_tracker/__init__.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam3_tracker/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..dce9c5ca2c60c735e87adf73bce69c996f4a1241 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam3_tracker/__init__.py @@ -0,0 +1,29 @@ +# Copyright 2025 the HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +from typing import TYPE_CHECKING + +from ...utils import _LazyModule +from ...utils.import_utils import define_import_structure + + +if TYPE_CHECKING: + from .configuration_sam3_tracker import * + from .modeling_sam3_tracker import * + from .processing_sam3_tracker import * +else: + import sys + + _file = globals()["__file__"] + sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__) diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam3_tracker/configuration_sam3_tracker.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam3_tracker/configuration_sam3_tracker.py new file mode 100644 index 0000000000000000000000000000000000000000..4f43a086c813eca46a31fdfb82a84d0a266d8675 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam3_tracker/configuration_sam3_tracker.py @@ -0,0 +1,246 @@ +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# This file was automatically generated from src/transformers/models/sam3_tracker/modular_sam3_tracker.py. +# Do NOT edit this file manually as any edits will be overwritten by the generation of +# the file from the modular. If any change should be done, please apply the change to the +# modular_sam3_tracker.py file directly. One of our CI enforces this. +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# Copyright 2025 the HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +from ...configuration_utils import PreTrainedConfig +from ..auto import CONFIG_MAPPING, AutoConfig + + +class Sam3TrackerPromptEncoderConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`Sam3TrackerPromptEncoder`]. The [`Sam3TrackerPromptEncoder`] + module is used to encode the input 2D points and bounding boxes. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + hidden_size (`int`, *optional*, defaults to 256): + Dimensionality of the hidden states. + image_size (`int`, *optional*, defaults to 1008): + The expected output resolution of the image. + patch_size (`int`, *optional*, defaults to 14): + The size (resolution) of each patch. + mask_input_channels (`int`, *optional*, defaults to 16): + The number of channels to be fed to the `MaskDecoder` module. + num_point_embeddings (`int`, *optional*, defaults to 4): + The number of point embeddings to be used. + hidden_act (`str`, *optional*, defaults to `"gelu"`): + The non-linear activation function in the encoder and pooler. + layer_norm_eps (`float`, *optional*, defaults to 1e-06): + The epsilon used by the layer normalization layers. + scale (`float`, *optional*, defaults to 1): + The scale factor for the prompt encoder. + """ + + base_config_key = "prompt_encoder_config" + + def __init__( + self, + hidden_size=256, + image_size=1008, + patch_size=14, + mask_input_channels=16, + num_point_embeddings=4, + hidden_act="gelu", + layer_norm_eps=1e-6, + scale=1, + **kwargs, + ): + super().__init__(**kwargs) + self.hidden_size = hidden_size + self.image_size = image_size + self.patch_size = patch_size + self.mask_input_channels = mask_input_channels + self.num_point_embeddings = num_point_embeddings + self.hidden_act = hidden_act + self.layer_norm_eps = layer_norm_eps + self.scale = scale + + +class Sam3TrackerMaskDecoderConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`Sam3TrackerMaskDecoder`]. It is used to instantiate a SAM3_TRACKER + memory encoder according to the specified arguments, defining the model architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + hidden_size (`int`, *optional*, defaults to 256): + Dimensionality of the hidden states. + hidden_act (`str`, *optional*, defaults to `"gelu"`): + The non-linear activation function in the SAM3_TRACKER mask decoder. + mlp_dim (`int`, *optional*, defaults to 2048): + The dimension of the MLP in the two-way transformer. + num_hidden_layers (`int`, *optional*, defaults to 2): + The number of hidden layers in the two-way transformer. + num_attention_heads (`int`, *optional*, defaults to 8): + The number of attention heads in the two-way transformer. + attention_downsample_rate (`int`, *optional*, defaults to 2): + The downsample rate for the attention layers. + num_multimask_outputs (`int`, *optional*, defaults to 3): + The number of multimask outputs. + iou_head_depth (`int`, *optional*, defaults to 3): + The depth of the IoU head. + iou_head_hidden_dim (`int`, *optional*, defaults to 256): + The hidden dimension of the IoU head. + dynamic_multimask_via_stability (`bool`, *optional*, defaults to `True`): + Whether to use dynamic multimask via stability. + dynamic_multimask_stability_delta (`float`, *optional*, defaults to 0.05): + The stability delta for the dynamic multimask. + dynamic_multimask_stability_thresh (`float`, *optional*, defaults to 0.98): + The stability threshold for the dynamic multimask. + + """ + + base_config_key = "mask_decoder_config" + + def __init__( + self, + hidden_size=256, + hidden_act="gelu", + mlp_dim=2048, + num_hidden_layers=2, + num_attention_heads=8, + attention_downsample_rate=2, + num_multimask_outputs=3, + iou_head_depth=3, + iou_head_hidden_dim=256, + dynamic_multimask_via_stability=True, + dynamic_multimask_stability_delta=0.05, + dynamic_multimask_stability_thresh=0.98, + **kwargs, + ): + super().__init__(**kwargs) + + self.hidden_size = hidden_size + self.num_multimask_outputs = num_multimask_outputs + self.hidden_act = hidden_act + self.iou_head_depth = iou_head_depth + self.iou_head_hidden_dim = iou_head_hidden_dim + self.dynamic_multimask_via_stability = dynamic_multimask_via_stability + self.dynamic_multimask_stability_delta = dynamic_multimask_stability_delta + self.dynamic_multimask_stability_thresh = dynamic_multimask_stability_thresh + + # TwoWayTransformer configuration + self.num_hidden_layers = num_hidden_layers + self.hidden_size = hidden_size + self.num_attention_heads = num_attention_heads + self.mlp_dim = mlp_dim + self.attention_downsample_rate = attention_downsample_rate + + +class Sam3TrackerConfig(PreTrainedConfig): + r""" + [`Sam3TrackerConfig`] is the configuration class to store the configuration of a [`Sam3TrackerModel`]. It is used to instantiate a + SAM3_TRACKER model according to the specified arguments, defining the memory attention, memory encoder, and image encoder + configs. Instantiating a configuration defaults will yield a similar configuration to that of the SAM 2.1 Hiera-tiny + [facebook/sam3_tracker.1-hiera-tiny](https://huggingface.co/facebook/sam3_tracker.1-hiera-tiny) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + + + SAM3 Tracker checkpoints with `model_type="sam3_tracker_video"` are compatible with `Sam3TrackerModel` since the + video variant weights are a superset of the image-only model weights. You may see a warning about model type + mismatch when loading such checkpoints, which can be safely ignored in this case. + + + + Args: + vision_config (Union[`dict`, `Sam3TrackerVisionConfig`], *optional*): + Dictionary of configuration options used to initialize [`Sam3TrackerVisionConfig`]. + prompt_encoder_config (Union[`dict`, `Sam3TrackerPromptEncoderConfig`], *optional*): + Dictionary of configuration options used to initialize [`Sam3TrackerPromptEncoderConfig`]. + mask_decoder_config (Union[`dict`, `Sam3TrackerMaskDecoderConfig`], *optional*): + Dictionary of configuration options used to initialize [`Sam3TrackerMaskDecoderConfig`]. + initializer_range (`float`, *optional*, defaults to 0.02): + Standard deviation for parameter initialization. + + Example: + + ```python + >>> from transformers import ( + ... Sam3TrackerVisionConfig, + ... Sam3TrackerPromptEncoderConfig, + ... Sam3TrackerMaskDecoderConfig, + ... Sam3TrackerModel, + ... ) + + >>> # Initializing a Sam3TrackerConfig with `"facebook/sam3_tracker.1_hiera_tiny"` style configuration + >>> configuration = Sam3TrackerConfig() + + >>> # Initializing a Sam3TrackerModel (with random weights) from the `"facebook/sam3_tracker.1_hiera_tiny"` style configuration + >>> model = Sam3TrackerModel(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + + >>> # We can also initialize a Sam3TrackerConfig from a Sam3TrackerVisionConfig, Sam3TrackerPromptEncoderConfig, and Sam3TrackerMaskDecoderConfig + >>> # Initializing SAM3_TRACKER vision encoder, memory attention, and memory encoder configurations + >>> vision_config = Sam3TrackerVisionConfig() + >>> prompt_encoder_config = Sam3TrackerPromptEncoderConfig() + >>> mask_decoder_config = Sam3TrackerMaskDecoderConfig() + + >>> config = Sam3TrackerConfig(vision_config, prompt_encoder_config, mask_decoder_config) + ``` + """ + + model_type = "sam3_tracker" + sub_configs = { + "vision_config": AutoConfig, + "prompt_encoder_config": Sam3TrackerPromptEncoderConfig, + "mask_decoder_config": Sam3TrackerMaskDecoderConfig, + } + + def __init__( + self, + vision_config=None, + prompt_encoder_config=None, + mask_decoder_config=None, + initializer_range=0.02, + **kwargs, + ): + vision_config = ( + vision_config + if vision_config is not None + else {"backbone_feature_sizes": [[288, 288], [144, 144], [72, 72]]} + ) + prompt_encoder_config = prompt_encoder_config if prompt_encoder_config is not None else {} + mask_decoder_config = mask_decoder_config if mask_decoder_config is not None else {} + + if isinstance(vision_config, dict): + vision_config["model_type"] = vision_config.get("model_type", "sam3_vision_model") + vision_config = CONFIG_MAPPING[vision_config["model_type"]](**vision_config) + if isinstance(prompt_encoder_config, Sam3TrackerPromptEncoderConfig): + prompt_encoder_config = prompt_encoder_config.to_dict() + if isinstance(mask_decoder_config, Sam3TrackerMaskDecoderConfig): + mask_decoder_config = mask_decoder_config.to_dict() + + self.vision_config = vision_config + self.prompt_encoder_config = Sam3TrackerPromptEncoderConfig(**prompt_encoder_config) + self.mask_decoder_config = Sam3TrackerMaskDecoderConfig(**mask_decoder_config) + + self.initializer_range = initializer_range + super().__init__(**kwargs) + + +__all__ = ["Sam3TrackerConfig", "Sam3TrackerPromptEncoderConfig", "Sam3TrackerMaskDecoderConfig"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam3_tracker/modeling_sam3_tracker.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam3_tracker/modeling_sam3_tracker.py new file mode 100644 index 0000000000000000000000000000000000000000..651a8551bb9235eb1b04d220cf754979087b1d88 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam3_tracker/modeling_sam3_tracker.py @@ -0,0 +1,1109 @@ +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# This file was automatically generated from src/transformers/models/sam3_tracker/modular_sam3_tracker.py. +# Do NOT edit this file manually as any edits will be overwritten by the generation of +# the file from the modular. If any change should be done, please apply the change to the +# modular_sam3_tracker.py file directly. One of our CI enforces this. +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# Copyright 2025 the HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +from collections.abc import Callable +from dataclasses import dataclass + +import numpy as np +import torch +import torch.nn as nn +import torch.nn.functional as F +from torch import Tensor + +from ... import initialization as init +from ...activations import ACT2FN +from ...modeling_layers import GradientCheckpointingLayer +from ...modeling_outputs import BaseModelOutput, BaseModelOutputWithPooling +from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel +from ...processing_utils import Unpack +from ...utils import ModelOutput, auto_docstring, can_return_tuple, logging +from ...utils.generic import TransformersKwargs, is_flash_attention_requested, merge_with_config_defaults +from ...utils.output_capturing import OutputRecorder, capture_outputs +from ..auto import AutoModel +from .configuration_sam3_tracker import Sam3TrackerConfig, Sam3TrackerMaskDecoderConfig, Sam3TrackerPromptEncoderConfig + + +logger = logging.get_logger(__name__) + + +@dataclass +@auto_docstring(custom_intro="Base class for the Sam3Tracker model's output.") +class Sam3TrackerImageSegmentationOutput(ModelOutput): + r""" + iou_scores (`torch.FloatTensor` of shape `(batch_size, point_batch_size, num_masks)`): + The Intersection over Union (IoU) scores of the predicted masks. + pred_masks (`torch.FloatTensor` of shape `(batch_size, point_batch_size, num_masks, height, width)`): + The predicted low-resolution masks. This is an alias for `low_res_masks`. These masks need to be post-processed + by the processor to be brought to the original image size. + object_score_logits (`torch.FloatTensor` of shape `(batch_size, point_batch_size, 1)`): + Logits for the object score, indicating if an object is present. + image_embeddings (`tuple(torch.FloatTensor)`): + The features from the FPN, which are used by the mask decoder. This is a tuple of `torch.FloatTensor` where each + tensor has shape `(batch_size, channels, height, width)`. + vision_hidden_states (`tuple(torch.FloatTensor)`, *optional*, returned when `output_hidden_states=True`): + Tuple of `torch.FloatTensor` (one for the output of each stage) of shape `(batch_size, height, width, hidden_size)`. + Hidden-states of the vision model at the output of each stage. + vision_attentions (`tuple(torch.FloatTensor)`, *optional*, returned when `output_attentions=True`): + Tuple of `torch.FloatTensor` (one for each layer) of shape `(batch_size, num_heads, sequence_length, sequence_length)`. + Attentions weights of the vision model. + mask_decoder_attentions (`tuple(torch.FloatTensor)`, *optional*, returned when `output_attentions=True`): + Tuple of `torch.FloatTensor` (one for each layer) of shape `(batch_size, num_heads, sequence_length, sequence_length)`. + Attentions weights of the mask decoder. + """ + + iou_scores: torch.FloatTensor | None = None + pred_masks: torch.FloatTensor | None = None + object_score_logits: torch.FloatTensor | None = None + image_embeddings: tuple[torch.FloatTensor, ...] = None + vision_hidden_states: tuple[torch.FloatTensor, ...] | None = None + vision_attentions: tuple[torch.FloatTensor, ...] | None = None + mask_decoder_attentions: tuple[torch.FloatTensor, ...] | None = None + + +class Sam3TrackerFeedForward(nn.Module): + def __init__( + self, + input_dim: int, + hidden_dim: int, + output_dim: int, + num_layers: int, + activation: str = "relu", + sigmoid_output: bool = False, + ): + super().__init__() + self.num_layers = num_layers + self.activation = ACT2FN[activation] + self.proj_in = nn.Linear(input_dim, hidden_dim) + self.proj_out = nn.Linear(hidden_dim, output_dim) + self.layers = nn.ModuleList([nn.Linear(hidden_dim, hidden_dim) for _ in range(num_layers - 2)]) + self.sigmoid_output = sigmoid_output + + def forward(self, hidden_states): + hidden_states = self.proj_in(hidden_states) + hidden_states = self.activation(hidden_states) + for layer in self.layers: + hidden_states = self.activation(layer(hidden_states)) + + hidden_states = self.proj_out(hidden_states) + if self.sigmoid_output: + hidden_states = F.sigmoid(hidden_states) + return hidden_states + + +@auto_docstring( + custom_intro=""" + Segment Anything Model 3 (SAM 3) for generating segmentation masks, given an input image and + input points and labels, boxes, or masks. + """ +) +class Sam3TrackerPreTrainedModel(PreTrainedModel): + config_class = Sam3TrackerConfig + base_model_prefix = "sam3_tracker" + main_input_name = "pixel_values" + input_modalities = ("image",) + _supports_sdpa = True + _supports_flash_attn = True + _supports_attention_backend = True + _keys_to_ignore_on_load_unexpected = [ + r"^memory_.*", + r"^mask_downsample.*", + r"^object_pointer_proj.*", + r"^temporal_positional_encoding_projection_layer.*", + "no_memory_positional_encoding", + "no_object_pointer", + "occlusion_spatial_embedding_parameter", + ] + + @torch.no_grad() + def _init_weights(self, module): + super()._init_weights(module) + if isinstance(module, Sam3TrackerModel): + if module.no_memory_embedding is not None: + init.zeros_(module.no_memory_embedding) + elif isinstance(module, Sam3TrackerPositionalEmbedding): + init.normal_(module.positional_embedding, std=module.scale) + + +class Sam3TrackerPositionalEmbedding(nn.Module): + def __init__(self, config: Sam3TrackerPromptEncoderConfig): + super().__init__() + self.scale = config.scale + positional_embedding = self.scale * torch.randn((2, config.hidden_size // 2)) + self.register_buffer("positional_embedding", positional_embedding) + + def forward(self, input_coords, input_shape=None): + """Positionally encode points that are normalized to [0,1].""" + coordinates = input_coords.clone() + + if input_shape is not None: + coordinates[:, :, :, 0] = coordinates[:, :, :, 0] / input_shape[1] + coordinates[:, :, :, 1] = coordinates[:, :, :, 1] / input_shape[0] + coordinates.to(torch.float32) + + # assuming coords are in [0, 1]^2 square and have d_1 x ... x d_n x 2 shape + coordinates = 2 * coordinates - 1 + coordinates = coordinates.to(self.positional_embedding.dtype) + coordinates = coordinates @ self.positional_embedding + coordinates = 2 * np.pi * coordinates + # outputs d_1 x ... x d_n x channel shape + return torch.cat([torch.sin(coordinates), torch.cos(coordinates)], dim=-1) + + +class Sam3TrackerMaskEmbedding(nn.Module): + def __init__(self, config: Sam3TrackerPromptEncoderConfig): + super().__init__() + self.mask_input_channels = config.mask_input_channels // 4 + self.activation = ACT2FN[config.hidden_act] + self.conv1 = nn.Conv2d(1, self.mask_input_channels, kernel_size=2, stride=2) + self.conv2 = nn.Conv2d(self.mask_input_channels, config.mask_input_channels, kernel_size=2, stride=2) + self.conv3 = nn.Conv2d(config.mask_input_channels, config.hidden_size, kernel_size=1) + self.layer_norm1 = Sam3TrackerLayerNorm( + self.mask_input_channels, eps=config.layer_norm_eps, data_format="channels_first" + ) + self.layer_norm2 = Sam3TrackerLayerNorm( + self.mask_input_channels * 4, eps=config.layer_norm_eps, data_format="channels_first" + ) + + def forward(self, masks): + hidden_states = self.conv1(masks) + hidden_states = self.layer_norm1(hidden_states) + hidden_states = self.activation(hidden_states) + + hidden_states = self.conv2(hidden_states) + hidden_states = self.layer_norm2(hidden_states) + hidden_states = self.activation(hidden_states) + dense_embeddings = self.conv3(hidden_states) + return dense_embeddings + + +class Sam3TrackerPromptEncoder(nn.Module): + def __init__(self, config: Sam3TrackerPromptEncoderConfig): + super().__init__() + self.shared_embedding = Sam3TrackerPositionalEmbedding(config) + self.mask_embed = Sam3TrackerMaskEmbedding(config) + self.no_mask_embed = nn.Embedding(1, config.hidden_size) + + self.image_embedding_size = (config.image_size // config.patch_size, config.image_size // config.patch_size) + self.mask_input_size = (4 * config.image_size // config.patch_size, 4 * config.image_size // config.patch_size) + self.input_image_size = config.image_size + + self.point_embed = nn.Embedding(config.num_point_embeddings, config.hidden_size) + self.hidden_size = config.hidden_size + self.not_a_point_embed = nn.Embedding(1, config.hidden_size) + + def _embed_points(self, points: torch.Tensor, labels: torch.Tensor, pad: bool) -> torch.Tensor: + """Embeds point prompts.""" + points = points + 0.5 # Shift to center of pixel + if pad: + points = torch.nn.functional.pad(points, (0, 0, 0, 1), mode="constant", value=0) + labels = torch.nn.functional.pad(labels, (0, 1), mode="constant", value=-1) + input_shape = (self.input_image_size, self.input_image_size) + point_embedding = self.shared_embedding(points, input_shape) + + # torch.where and expanding the labels tensor is required by the ONNX export + point_embedding = torch.where(labels[..., None] == -1, self.not_a_point_embed.weight, point_embedding) + + # This is required for the ONNX export. The dtype, device need to be explicitly + # specified as otherwise torch.onnx.export interprets as double + point_embedding = torch.where( + labels[..., None] != -10, + point_embedding, + torch.zeros_like(point_embedding), + ) + + # Add point embeddings for labels >= 0 + point_embedding = point_embedding + self.point_embed(labels.clamp(min=0)) * (labels >= 0).unsqueeze(-1) + + return point_embedding + + def _embed_boxes(self, boxes: torch.Tensor) -> torch.Tensor: + """Embeds box prompts.""" + boxes = boxes + 0.5 # Shift to center of pixel + coords = boxes.view(*boxes.shape[:2], 2, 2) + # add padding point for consistency with the original implementation + coords = torch.nn.functional.pad(coords, (0, 0, 0, 1), mode="constant", value=0) + corner_embedding = self.shared_embedding(coords, (self.input_image_size, self.input_image_size)) + corner_embedding[:, :, 0, :] += self.point_embed.weight[2] + corner_embedding[:, :, 1, :] += self.point_embed.weight[3] + corner_embedding[:, :, 2, :] = self.not_a_point_embed.weight.expand_as(corner_embedding[:, :, 2, :]) + return corner_embedding + + def forward( + self, + input_points: tuple[torch.Tensor, torch.Tensor] | None, + input_labels: torch.Tensor | None, + input_boxes: torch.Tensor | None, + input_masks: torch.Tensor | None, + ) -> tuple[torch.Tensor, torch.Tensor]: + """ + Embeds different types of prompts, returning both sparse and dense embeddings. + + Args: + points (`torch.Tensor`, *optional*): + point coordinates and labels to embed. + boxes (`torch.Tensor`, *optional*): + boxes to embed + masks (`torch.Tensor`, *optional*): + masks to embed + """ + sparse_embeddings = None + batch_size = 1 + if input_points is not None: + batch_size = input_points.shape[0] + if input_labels is None: + raise ValueError("If points are provided, labels must also be provided.") + point_embeddings = self._embed_points(input_points, input_labels, pad=(input_boxes is None)) + sparse_embeddings = point_embeddings + if input_boxes is not None: + batch_size = input_boxes.shape[0] + box_embeddings = self._embed_boxes(input_boxes) + if sparse_embeddings is None: + sparse_embeddings = box_embeddings + else: + sparse_embeddings = torch.cat([sparse_embeddings, box_embeddings], dim=2) + if input_masks is not None: + dense_embeddings = self.mask_embed(input_masks) + else: + dense_embeddings = self.no_mask_embed.weight.reshape(1, -1, 1, 1).expand( + batch_size, -1, self.image_embedding_size[0], self.image_embedding_size[1] + ) + + return sparse_embeddings, dense_embeddings + + +def eager_attention_forward( + module: nn.Module, + query: torch.Tensor, + key: torch.Tensor, + value: torch.Tensor, + attention_mask: torch.Tensor | None, + scaling: float, + dropout: float = 0.0, + **kwargs, +): + attn_weights = torch.matmul(query, key.transpose(2, 3)) * scaling + if attention_mask is not None: + attn_weights = attn_weights + attention_mask + + attn_weights = nn.functional.softmax(attn_weights, dim=-1, dtype=torch.float32).to(query.dtype) + attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training) + attn_output = torch.matmul(attn_weights, value) + attn_output = attn_output.transpose(1, 2).contiguous() + + return attn_output, attn_weights + + +class Sam3TrackerAttention(nn.Module): + """ + SAM3_TRACKER's attention layer that allows for downscaling the size of the embedding after projection to queries, keys, and + values. + """ + + def __init__(self, config, downsample_rate=None): + super().__init__() + downsample_rate = config.attention_downsample_rate if downsample_rate is None else downsample_rate + self.config = config + self.hidden_size = config.hidden_size + self.internal_dim = config.hidden_size // downsample_rate + self.num_attention_heads = config.num_attention_heads + self.head_dim = self.internal_dim // config.num_attention_heads + self.scaling = self.head_dim**-0.5 + self.is_causal = False + + self.q_proj = nn.Linear(self.hidden_size, self.internal_dim) + self.k_proj = nn.Linear(self.hidden_size, self.internal_dim) + self.v_proj = nn.Linear(self.hidden_size, self.internal_dim) + self.o_proj = nn.Linear(self.internal_dim, self.hidden_size) + + def forward( + self, + query: torch.Tensor, + key: torch.Tensor, + value: torch.Tensor, + attention_similarity: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor, torch.Tensor]: + # Input projections + batch_size, point_batch_size = query.shape[:2] + new_shape = (batch_size * point_batch_size, -1, self.num_attention_heads, self.head_dim) + + query = self.q_proj(query).view(*new_shape).transpose(1, 2) + key = self.k_proj(key).view(*new_shape).transpose(1, 2) + value = self.v_proj(value).view(*new_shape).transpose(1, 2) + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, eager_attention_forward + ) + + if is_flash_attention_requested(self.config) and attention_similarity is not None: + # Target guided masks are represented as float masks and are incompatible with Flash Attention + # Fallback to SDPA for this call only so the rest of the model can still benefit from FA + attention_interface = ALL_ATTENTION_FUNCTIONS["sdpa"] + logger.warning_once( + "Falling back to SDPA for target-guided attention because " + "Flash Attention does not support additive bias masks." + ) + + attn_output, attn_weights = attention_interface( + self, + query, + key, + value, + attention_mask=attention_similarity, + dropout=0.0, + scaling=self.scaling, + is_causal=self.is_causal, + **kwargs, + ) + + attn_output = attn_output.reshape( + batch_size, point_batch_size, -1, self.num_attention_heads * self.head_dim + ).contiguous() + attn_output = self.o_proj(attn_output) + + return attn_output, attn_weights + + +class Sam3TrackerTwoWayAttentionBlock(GradientCheckpointingLayer): + def __init__(self, config: Sam3TrackerMaskDecoderConfig, skip_first_layer_pe: bool = False): + """ + A transformer block with four layers: + (1) self-attention of sparse inputs (2) cross attention of sparse inputs -> dense inputs (3) mlp block on + sparse inputs (4) cross attention of dense inputs -> sparse inputs + + Arguments: + config (`Sam3TrackerMaskDecoderConfig`): + The configuration file used to instantiate the block + attention_downsample_rate (*optionalk*, int, defaults to 2): + The downsample ratio of the block used to reduce the inner dim of the attention. + skip_first_layer_pe (*optional*, bool, defaults to `False`): + Whether or not to skip the addition of the query_point_embedding on the first layer. + """ + super().__init__() + self.self_attn = Sam3TrackerAttention(config, downsample_rate=1) + self.layer_norm1 = nn.LayerNorm(config.hidden_size) + + self.cross_attn_token_to_image = Sam3TrackerAttention(config) + self.layer_norm2 = nn.LayerNorm(config.hidden_size) + + self.mlp = Sam3TrackerFeedForward( + config.hidden_size, config.mlp_dim, config.hidden_size, num_layers=config.num_hidden_layers + ) + self.layer_norm3 = nn.LayerNorm(config.hidden_size) + + self.layer_norm4 = nn.LayerNorm(config.hidden_size) + self.cross_attn_image_to_token = Sam3TrackerAttention(config) + + self.skip_first_layer_pe = skip_first_layer_pe + + def forward( + self, + queries: Tensor, + keys: Tensor, + query_point_embedding: Tensor, + key_point_embedding: Tensor, + attention_similarity: Tensor, + **kwargs: Unpack[TransformersKwargs], + ): + # Self attention block + if self.skip_first_layer_pe: + queries, _ = self.self_attn(query=queries, key=queries, value=queries) + else: + query = queries + query_point_embedding + attn_out, _ = self.self_attn(query=query, key=query, value=queries) + queries = queries + attn_out + queries = self.layer_norm1(queries) + + # Cross attention block, tokens attending to image embedding + query = queries + query_point_embedding + key = keys + key_point_embedding + + attn_out, _ = self.cross_attn_token_to_image( + query=query, key=key, value=keys, attention_similarity=attention_similarity + ) + queries = queries + attn_out + + queries = self.layer_norm2(queries) + + # MLP block + mlp_out = self.mlp(queries) + queries = queries + mlp_out + queries = self.layer_norm3(queries) + + # Cross attention block, image embedding attending to tokens + query = queries + query_point_embedding + key = keys + key_point_embedding + + attn_out, _ = self.cross_attn_image_to_token(query=key, key=query, value=queries) + keys = keys + attn_out + + keys = self.layer_norm4(keys) + return queries, keys, attn_out + + +class Sam3TrackerTwoWayTransformer(nn.Module): + def __init__(self, config: Sam3TrackerMaskDecoderConfig): + super().__init__() + self.config = config + + self.num_hidden_layers = config.num_hidden_layers + self.layers = nn.ModuleList() + + for i in range(self.num_hidden_layers): + self.layers.append(Sam3TrackerTwoWayAttentionBlock(config, skip_first_layer_pe=(i == 0))) + + self.final_attn_token_to_image = Sam3TrackerAttention(config) + self.layer_norm_final_attn = nn.LayerNorm(config.hidden_size) + + def forward( + self, + point_embeddings: Tensor, + image_embeddings: Tensor, + image_positional_embeddings: Tensor, + attention_similarity: Tensor, + target_embedding=None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple | BaseModelOutput: + if image_embeddings is None: + raise ValueError("You have to specify an image_embedding") + + image_embeddings = image_embeddings.flatten(2).permute(0, 2, 1).unsqueeze(1) + image_positional_embeddings = image_positional_embeddings.flatten(2).permute(0, 2, 1).unsqueeze(1) + + # Prepare queries + queries = point_embeddings + keys = image_embeddings + + # Apply transformer blocks and final layernorm + for layer in self.layers: + if target_embedding is not None: + queries += target_embedding + + queries, keys, _ = layer( + queries=queries, + keys=keys, + query_point_embedding=point_embeddings, + key_point_embedding=image_positional_embeddings, + attention_similarity=attention_similarity, + **kwargs, + ) + # Apply the final attention layer from the points to the image + query = queries + point_embeddings + key = keys + image_positional_embeddings + + attn_out, _ = self.final_attn_token_to_image(query=query, key=key, value=keys) + + queries = queries + attn_out + queries = self.layer_norm_final_attn(queries) + return queries, keys + + +class Sam3TrackerLayerNorm(nn.LayerNorm): + r"""LayerNorm that supports two data formats: channels_last (default) or channels_first. + The ordering of the dimensions in the inputs. channels_last corresponds to inputs with shape (batch_size, height, + width, channels) while channels_first corresponds to inputs with shape (batch_size, channels, height, width). + """ + + def __init__(self, normalized_shape, *, eps=1e-6, data_format="channels_last", **kwargs): + super().__init__(normalized_shape, eps=eps, **kwargs) + if data_format not in ["channels_last", "channels_first"]: + raise NotImplementedError(f"Unsupported data format: {data_format}") + self.data_format = data_format + + def forward(self, features: torch.Tensor) -> torch.Tensor: + """ + Args: + features: Tensor of shape (batch_size, channels, height, width) OR (batch_size, height, width, channels) + """ + if self.data_format == "channels_first": + features = features.permute(0, 2, 3, 1) + features = super().forward(features) + features = features.permute(0, 3, 1, 2) + else: + features = super().forward(features) + return features + + +class Sam3TrackerMaskDecoder(nn.Module): + def __init__(self, config: Sam3TrackerMaskDecoderConfig): + super().__init__() + self.config = config + self.hidden_size = config.hidden_size + + self.num_multimask_outputs = config.num_multimask_outputs + self.num_mask_tokens = config.num_multimask_outputs + 1 + + self.iou_token = nn.Embedding(1, self.hidden_size) + self.mask_tokens = nn.Embedding(self.num_mask_tokens, self.hidden_size) + + self.transformer = Sam3TrackerTwoWayTransformer(config) + + # should we create a new class for this? + self.upscale_conv1 = nn.ConvTranspose2d(self.hidden_size, self.hidden_size // 4, kernel_size=2, stride=2) + self.upscale_conv2 = nn.ConvTranspose2d(self.hidden_size // 4, self.hidden_size // 8, kernel_size=2, stride=2) + self.upscale_layer_norm = Sam3TrackerLayerNorm(self.hidden_size // 4, data_format="channels_first") + self.activation = nn.GELU() + + mlps_list = [] + for _ in range(self.num_mask_tokens): + mlps_list += [Sam3TrackerFeedForward(self.hidden_size, self.hidden_size, self.hidden_size // 8, 3)] + self.output_hypernetworks_mlps = nn.ModuleList(mlps_list) + self.iou_prediction_head = Sam3TrackerFeedForward( + self.hidden_size, + config.iou_head_hidden_dim, + self.num_mask_tokens, + config.iou_head_depth, + sigmoid_output=True, + ) + + self.conv_s0 = nn.Conv2d(config.hidden_size, config.hidden_size // 8, kernel_size=1, stride=1) + self.conv_s1 = nn.Conv2d(config.hidden_size, config.hidden_size // 4, kernel_size=1, stride=1) + + self.obj_score_token = nn.Embedding(1, self.hidden_size) + self.pred_obj_score_head = Sam3TrackerFeedForward(self.hidden_size, self.hidden_size, 1, 3) + + self.dynamic_multimask_via_stability = config.dynamic_multimask_via_stability + self.dynamic_multimask_stability_delta = config.dynamic_multimask_stability_delta + self.dynamic_multimask_stability_thresh = config.dynamic_multimask_stability_thresh + + def forward( + self, + image_embeddings: torch.Tensor, + image_positional_embeddings: torch.Tensor, + sparse_prompt_embeddings: torch.Tensor, + dense_prompt_embeddings: torch.Tensor, + multimask_output: bool, + high_resolution_features: list[torch.Tensor], + attention_similarity: torch.Tensor | None = None, + target_embedding: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor, torch.Tensor, torch.Tensor, torch.Tensor]: + """ + Predict masks given image and prompt embeddings. + + Args: + image_embeddings (`torch.Tensor`): + The embeddings from the image encoder. + image_positional_embeddings (`torch.Tensor`): + Positional encoding with the shape of image_embeddings. + sparse_prompt_embeddings (`torch.Tensor`): + The embeddings of the points and boxes. + dense_prompt_embeddings (`torch.Tensor`): + The embeddings of the mask inputs. + multimask_output (`bool`): + Whether to return multiple masks or a single mask. + high_resolution_features (`list[torch.Tensor]`, *optional*): + The high-resolution features from the vision encoder. + attention_similarity (`torch.Tensor`, *optional*): + The attention similarity tensor. + target_embedding (`torch.Tensor`, *optional*): + The target embedding. + """ + batch_size, num_channels, height, width = image_embeddings.shape + point_batch_size = sparse_prompt_embeddings.shape[1] + # Concatenate output tokens + output_tokens = torch.cat( + [ + self.obj_score_token.weight, + self.iou_token.weight, + self.mask_tokens.weight, + ], + dim=0, + ) + output_tokens = output_tokens.repeat(batch_size, point_batch_size, 1, 1) + + if sparse_prompt_embeddings.shape[0] != 0: + tokens = torch.cat((output_tokens, sparse_prompt_embeddings), dim=2) + else: + tokens = output_tokens + point_embeddings = tokens.to(self.iou_token.weight.dtype) + + # Expand per-image data in batch direction to be per-mask + image_embeddings = image_embeddings + dense_prompt_embeddings + image_embeddings = image_embeddings.repeat_interleave(point_batch_size, dim=0) + image_positional_embeddings = image_positional_embeddings.repeat_interleave(point_batch_size, 0) + # Run the transformer + point_embeddings, image_embeddings = self.transformer( + point_embeddings=point_embeddings, + image_embeddings=image_embeddings, + image_positional_embeddings=image_positional_embeddings, + attention_similarity=attention_similarity, + target_embedding=target_embedding, + **kwargs, + ) + iou_token_out = point_embeddings[:, :, 1, :] + mask_tokens_out = point_embeddings[:, :, 2 : (2 + self.num_mask_tokens), :] + + # Upscale mask embeddings and predict masks using the mask tokens + image_embeddings = image_embeddings.transpose(2, 3).view( + batch_size * point_batch_size, num_channels, height, width + ) + + feat_s0, feat_s1 = high_resolution_features + feat_s0 = feat_s0.repeat_interleave(point_batch_size, dim=0) + feat_s1 = feat_s1.repeat_interleave(point_batch_size, dim=0) + upscaled_embedding = self.upscale_conv1(image_embeddings) + feat_s1 + upscaled_embedding = self.activation(self.upscale_layer_norm(upscaled_embedding)) + upscaled_embedding = self.activation(self.upscale_conv2(upscaled_embedding) + feat_s0) + + hyper_in_list: list[torch.Tensor] = [] + for i in range(self.num_mask_tokens): + current_mlp = self.output_hypernetworks_mlps[i] + hyper_in_list += [current_mlp(mask_tokens_out[:, :, i, :])] + hyper_in = torch.stack(hyper_in_list, dim=2) + + _, num_channels, height, width = upscaled_embedding.shape + upscaled_embedding = upscaled_embedding.view(batch_size, point_batch_size, num_channels, height * width) + masks = (hyper_in @ upscaled_embedding).view(batch_size, point_batch_size, -1, height, width) + + # Generate mask quality predictions + iou_pred = self.iou_prediction_head(iou_token_out) + object_score_logits = self.pred_obj_score_head(point_embeddings[:, :, 0, :]) + + # Select the correct mask or masks for output + if multimask_output: + mask_slice = slice(1, None) + masks = masks[:, :, mask_slice, :, :] + iou_pred = iou_pred[:, :, mask_slice] + elif self.dynamic_multimask_via_stability and not self.training: + mask_slice = slice(0, 1) + masks, iou_pred = self._dynamic_multimask_via_stability(masks, iou_pred) + else: + mask_slice = slice(0, 1) + masks = masks[:, :, mask_slice, :, :] + iou_pred = iou_pred[:, :, mask_slice] + + sam_tokens_out = mask_tokens_out[:, :, mask_slice] # [b, 3, c] shape + + return masks, iou_pred, sam_tokens_out, object_score_logits + + def _get_stability_scores(self, mask_logits): + """ + Compute stability scores of the mask logits based on the IoU between upper and + lower thresholds. + """ + mask_logits = mask_logits.flatten(-2) + stability_delta = self.dynamic_multimask_stability_delta + area_i = torch.sum(mask_logits > stability_delta, dim=-1).float() + area_u = torch.sum(mask_logits > -stability_delta, dim=-1).float() + stability_scores = torch.where(area_u > 0, area_i / area_u, 1.0) + return stability_scores + + def _dynamic_multimask_via_stability(self, all_mask_logits, all_iou_scores): + """ + When outputting a single mask, if the stability score from the current single-mask + output (based on output token 0) falls below a threshold, we instead select from + multi-mask outputs (based on output token 1~3) the mask with the highest predicted + IoU score. This is intended to ensure a valid mask for both clicking and tracking. + """ + # The best mask from multimask output tokens (1~3) + multimask_logits = all_mask_logits[:, :, 1:, :, :] + multimask_iou_scores = all_iou_scores[:, :, 1:] + best_scores_inds = torch.argmax(multimask_iou_scores, dim=-1) # [B, P] + best_scores_inds_expanded = best_scores_inds.unsqueeze(-1).unsqueeze(-1).unsqueeze(-1) + best_scores_inds_expanded = best_scores_inds_expanded.expand( + -1, -1, 1, multimask_logits.size(-2), multimask_logits.size(-1) + ) + best_multimask_logits = torch.gather(multimask_logits, 2, best_scores_inds_expanded) # [B, P, 1, H, W] + best_multimask_iou_scores = torch.gather(multimask_iou_scores, 2, best_scores_inds.unsqueeze(-1)) # [B, P, 1] + + # The mask from singlemask output token 0 and its stability score + singlemask_logits = all_mask_logits[:, :, 0:1, :, :] + singlemask_iou_scores = all_iou_scores[:, :, 0:1] + stability_scores = self._get_stability_scores(singlemask_logits) + is_stable = stability_scores >= self.dynamic_multimask_stability_thresh + + # Dynamically fall back to best multimask output upon low stability scores. + mask_logits_out = torch.where( + is_stable[..., None, None].expand_as(singlemask_logits), + singlemask_logits, + best_multimask_logits, + ) + iou_scores_out = torch.where( + is_stable.expand_as(singlemask_iou_scores), + singlemask_iou_scores, + best_multimask_iou_scores, + ) + return mask_logits_out, iou_scores_out + + +@dataclass +@auto_docstring(custom_intro="Base class for the vision encoder's outputs.") +class Sam3TrackerVisionEncoderOutput(BaseModelOutputWithPooling): + r""" + last_hidden_state (`torch.FloatTensor` of shape `(batch_size, height, width, hidden_size)`): + Sequence of hidden-states at the output of the last layer of the model. + hidden_states (`tuple(torch.FloatTensor)`, *optional*, returned when `output_hidden_states=True` is passed or when `config.output_hidden_states=True`): + Tuple of `torch.FloatTensor` (one for the output of the embeddings, if the model has an embedding layer, + + one for the output of each stage) of shape `(batch_size, height, width, hidden_size)`. Hidden-states of the + model at the output of each stage. + attentions (`tuple(torch.FloatTensor)`, *optional*, returned when `output_attentions=True` is passed or when `config.output_attentions=True`): + Tuple of `torch.FloatTensor` (one for each layer) of shape `(batch_size, num_heads, sequence_length, + sequence_length)`. Attentions weights after the attention softmax, used to compute the weighted average in + the self-attention heads. + fpn_hidden_states (`tuple(torch.FloatTensor)`): + Tuple of `torch.FloatTensor` (one for each feature level, from high to low resolution) of shape + `(batch_size, hidden_size, height, width)`. Feature maps from the Feature Pyramid Network neck. + fpn_position_encoding (`tuple(torch.FloatTensor)`): + Tuple of `torch.FloatTensor` (one for each feature level, from high to low resolution) of shape + `(batch_size, hidden_size, height, width)`. Positional encodings corresponding to the `fpn_hidden_states`. + """ + + fpn_hidden_states: torch.FloatTensor | None = None + fpn_position_encoding: torch.FloatTensor | None = None + + +@auto_docstring( + custom_intro=""" + Segment Anything Model 2 (SAM 2) for generating segmentation masks, given an input image and + input points and labels, boxes, or masks. + """ +) +class Sam3TrackerModel(Sam3TrackerPreTrainedModel): + input_modalities = ("image", "text") + _can_record_outputs = {"mask_decoder_attentions": OutputRecorder(Sam3TrackerTwoWayAttentionBlock, index=2)} + _tied_weights_keys = {} + _checkpoint_conversion_mapping = { + r"tracker_model.(.+)": r"\1", # the regex allows to remove the prefix, and add it back in revert mode + "detector_model.vision_encoder.backbone.": "vision_encoder.backbone.", + "tracker_neck.": "vision_encoder.neck.", + } + _keys_to_ignore_on_load_unexpected = [ + r"^detector_model.", + r"^memory_.*", + r"^mask_downsample.*", + r"^object_pointer_proj.*", + r"^temporal_positional_encoding_projection_layer.*", + "no_memory_positional_encoding", + "no_object_pointer", + "occlusion_spatial_embedding_parameter", + ] + + def __init__(self, config: Sam3TrackerConfig): + # loading from a sam3_video config + if hasattr(config, "tracker_config") and config.tracker_config is not None: + if isinstance(config.tracker_config, dict): + config.tracker_config = Sam3TrackerConfig(**config.tracker_config) + config = config.tracker_config + super().__init__(config) + self.shared_image_embedding = Sam3TrackerPositionalEmbedding(config.prompt_encoder_config) + self.vision_encoder = AutoModel.from_config(config.vision_config) + self.prompt_encoder = Sam3TrackerPromptEncoder(config.prompt_encoder_config) + # The module using it is not a PreTrainedModel subclass so we need this + config.mask_decoder_config._attn_implementation = config._attn_implementation + self.mask_decoder = Sam3TrackerMaskDecoder(config.mask_decoder_config) + + self.backbone_feature_sizes = config.vision_config.backbone_feature_sizes + # a single token to indicate no memory embedding from previous frames + self.hidden_dim = config.vision_config.fpn_hidden_size + self.no_memory_embedding = torch.nn.Parameter(torch.zeros(1, 1, self.hidden_dim)) + + self.post_init() + + def get_input_embeddings(self): + return self.vision_encoder.get_input_embeddings() + + def get_image_wide_positional_embeddings(self) -> torch.Tensor: + size = self.prompt_encoder.image_embedding_size + target_device = self.shared_image_embedding.positional_embedding.device + target_dtype = self.shared_image_embedding.positional_embedding.dtype + grid = torch.ones(size, device=target_device, dtype=target_dtype) + y_embed = grid.cumsum(dim=0) - 0.5 + x_embed = grid.cumsum(dim=1) - 0.5 + y_embed = y_embed / size[0] + x_embed = x_embed / size[1] + + positional_embedding = self.shared_image_embedding(torch.stack([x_embed, y_embed], dim=-1)) + return positional_embedding.permute(2, 0, 1).unsqueeze(0) # channel x height x width + + @torch.no_grad() + def get_image_embeddings( + self, + pixel_values: torch.FloatTensor, + **kwargs: Unpack[TransformersKwargs], + ) -> list[torch.Tensor]: + r""" + Returns the image embeddings by passing the pixel values through the vision encoder. + + Args: + pixel_values (`torch.FloatTensor` of shape `(batch_size, num_channels, height, width)`): + Input pixel values + """ + batch_size = pixel_values.shape[0] + image_outputs = self.get_image_features(pixel_values, return_dict=True, **kwargs) + feature_maps = image_outputs.fpn_hidden_states + + # add no memory embedding to the last feature map + feature_maps[-1] = feature_maps[-1] + self.no_memory_embedding + + # reshape feature maps to the same shape as the backbone feature sizes + image_embeddings = [ + feat.permute(1, 2, 0).view(batch_size, -1, *feat_size) + for feat, feat_size in zip(feature_maps, self.backbone_feature_sizes) + ] + + return image_embeddings + + @torch.no_grad() + def get_prompt_embeddings( + self, + input_points: torch.FloatTensor | None = None, + input_labels: torch.LongTensor | None = None, + input_boxes: torch.FloatTensor | None = None, + input_masks: torch.LongTensor | None = None, + ): + r""" + Returns the prompt embeddings by passing the input points, labels, boxes and masks through the prompt encoder. + + Args: + input_points (`torch.FloatTensor` of shape `(batch_size, point_batch_size, num_points_per_image, 2)`): + Optional input points for the prompt encoder. The padding of the point is automatically done by the + processor. `point_batch_size` refers to the number of masks that we want the model to predict per + point. The model will output `point_batch_size` times 3 masks in total. + input_labels (`torch.LongTensor` of shape `(batch_size, point_batch_size, num_points_per_image)`): + Optional input labels for the prompt encoder. The padding of the labels is automatically done by the + processor, or can be fed by the user. + input_boxes (`torch.FloatTensor` of shape `(batch_size, num_boxes_per_image, 4)`): + Optional input boxes for the prompt encoder. The padding of the boxes is automatically done by the + processor. users can also pass manually the input boxes. + input_masks (`torch.LongTensor` of shape `(batch_size, image_size, image_size)`): + Optional input masks for the prompt encoder. + """ + prompt_output = self.prompt_encoder( + input_points=input_points, + input_labels=input_labels, + input_boxes=input_boxes, + input_masks=input_masks, + ) + return prompt_output + + @merge_with_config_defaults + @capture_outputs + @auto_docstring + def forward( + self, + pixel_values: torch.FloatTensor | None = None, + input_points: torch.FloatTensor | None = None, + input_labels: torch.LongTensor | None = None, + input_boxes: torch.FloatTensor | None = None, + input_masks: torch.LongTensor | None = None, + image_embeddings: torch.FloatTensor | None = None, + multimask_output: bool = True, + attention_similarity: torch.FloatTensor | None = None, + target_embedding: torch.FloatTensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> Sam3TrackerImageSegmentationOutput: + r""" + input_points (`torch.FloatTensor` of shape `(batch_size, num_points, 2)`): + Input 2D spatial points, this is used by the prompt encoder to encode the prompt. Generally yields to much + better results. The points can be obtained by passing a list of list of list to the processor that will + create corresponding `torch` tensors of dimension 4. The first dimension is the image batch size, the + second dimension is the point batch size (i.e. how many segmentation masks do we want the model to predict + per input point), the third dimension is the number of points per segmentation mask (it is possible to pass + multiple points for a single mask), and the last dimension is the x (vertical) and y (horizontal) + coordinates of the point. If a different number of points is passed either for each image, or for each + mask, the processor will create "PAD" points that will correspond to the (0, 0) coordinate, and the + computation of the embedding will be skipped for these points using the labels. + input_labels (`torch.LongTensor` of shape `(batch_size, point_batch_size, num_points)`): + Input labels for the points, this is used by the prompt encoder to encode the prompt. According to the + official implementation, there are 3 types of labels + + - `1`: the point is a point that contains the object of interest + - `0`: the point is a point that does not contain the object of interest + - `-1`: the point corresponds to the background + + We added the label: + + - `-10`: the point is a padding point, thus should be ignored by the prompt encoder + + The padding labels should be automatically done by the processor. + input_boxes (`torch.FloatTensor` of shape `(batch_size, num_boxes, 4)`): + Input boxes for the points, this is used by the prompt encoder to encode the prompt. Generally yields to + much better generated masks. The boxes can be obtained by passing a list of list of list to the processor, + that will generate a `torch` tensor, with each dimension corresponding respectively to the image batch + size, the number of boxes per image and the coordinates of the top left and bottom right point of the box. + In the order (`x1`, `y1`, `x2`, `y2`): + + - `x1`: the x coordinate of the top left point of the input box + - `y1`: the y coordinate of the top left point of the input box + - `x2`: the x coordinate of the bottom right point of the input box + - `y2`: the y coordinate of the bottom right point of the input box + input_masks (`torch.FloatTensor` of shape `(batch_size, image_size, image_size)`): + SAM model also accepts segmentation masks as input. The mask will be embedded by the prompt encoder to + generate a corresponding embedding, that will be fed later on to the mask decoder. These masks needs to be + manually fed by the user, and they need to be of shape (`batch_size`, `image_size`, `image_size`). + image_embeddings (`torch.FloatTensor` of shape `(batch_size, output_channels, window_size, window_size)`): + Image embeddings, this is used by the mask decoder to generate masks and iou scores. For more memory + efficient computation, users can first retrieve the image embeddings using the `get_image_embeddings` + method, and then feed them to the `forward` method instead of feeding the `pixel_values`. + multimask_output (`bool`, *optional*): + In the original implementation and paper, the model always outputs 3 masks per image (or per point / per + bounding box if relevant). However, it is possible to just output a single mask, that corresponds to the + "best" mask, by specifying `multimask_output=False`. + attention_similarity (`torch.FloatTensor`, *optional*): + Attention similarity tensor, to be provided to the mask decoder for target-guided attention in case the + model is used for personalization as introduced in [PerSAM](https://huggingface.co/papers/2305.03048). + target_embedding (`torch.FloatTensor`, *optional*): + Embedding of the target concept, to be provided to the mask decoder for target-semantic prompting in case + the model is used for personalization as introduced in [PerSAM](https://huggingface.co/papers/2305.03048). + + Example: + + ```python + >>> from PIL import Image + >>> import httpx + >>> from io import BytesIO + >>> from transformers import AutoModel, AutoProcessor + + >>> model = AutoModel.from_pretrained("danelcsb/sam3_tracker.1_hiera_tiny") + >>> processor = AutoProcessor.from_pretrained("danelcsb/sam3_tracker.1_hiera_tiny") + + >>> url = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/model_doc/sam-car.png" + >>> with httpx.stream("GET", url) as response: + ... raw_image = Image.open(BytesIO(response.read())).convert("RGB") + >>> input_points = [[[400, 650]]] # 2D location of a window on the car + >>> inputs = processor(images=raw_image, input_points=input_points, return_tensors="pt") + + >>> # Get segmentation mask + >>> outputs = model(**inputs) + + >>> # Postprocess masks + >>> masks = processor.post_process_masks( + ... outputs.pred_masks, inputs["original_sizes"] + ... ) + ``` + """ + if not ((pixel_values is None) ^ (image_embeddings is None)): + raise ValueError("Exactly one of pixel_values or image_embeddings must be provided.") + if input_points is not None and input_boxes is not None: + if input_points.shape[1] != input_boxes.shape[1]: + raise ValueError( + f"You should provide as many bounding boxes as input points per box. Got {input_points.shape[1]} and {input_boxes.shape[1]}." + ) + + image_positional_embeddings = self.get_image_wide_positional_embeddings() + # repeat with batch size + batch_size = pixel_values.shape[0] if pixel_values is not None else image_embeddings[-1].shape[0] + image_positional_embeddings = image_positional_embeddings.repeat(batch_size, 1, 1, 1) + + vision_attentions = None + vision_hidden_states = None + + if pixel_values is not None: + image_outputs: Sam3TrackerVisionEncoderOutput = self.get_image_features( + pixel_values, return_dict=True, **kwargs + ) + feature_maps = image_outputs.fpn_hidden_states + vision_hidden_states = image_outputs.hidden_states + vision_attentions = image_outputs.attentions + + # add no memory embedding to the last feature map + feature_maps[-1] = feature_maps[-1] + self.no_memory_embedding + + # reshape feature maps to the same shape as the backbone feature sizes + image_embeddings = [ + feat.permute(1, 2, 0).view(batch_size, -1, *feat_size) + for feat, feat_size in zip(feature_maps, self.backbone_feature_sizes) + ] + + if input_points is not None and input_labels is None: + input_labels = torch.ones_like(input_points[:, :, :, 0], dtype=torch.int, device=input_points.device) + + if input_points is None and input_boxes is None: + # If no points are provide, pad with an empty point (with label -1) + input_points = torch.zeros( + batch_size, 1, 1, 2, dtype=image_embeddings[-1].dtype, device=image_embeddings[-1].device + ) + input_labels = -torch.ones(batch_size, 1, 1, dtype=torch.int32, device=image_embeddings[-1].device) + + if input_masks is not None: + # If mask_inputs is provided, downsize it into low-res mask input if needed + # and feed it as a dense mask prompt into the SAM mask encoder + if input_masks.shape[-2:] != self.prompt_encoder.mask_input_size: + input_masks = F.interpolate( + input_masks.float(), + size=self.prompt_encoder.mask_input_size, + align_corners=False, + mode="bilinear", + antialias=True, # use antialias for downsampling + ).to(input_masks.dtype) + + sparse_embeddings, dense_embeddings = self.prompt_encoder( + input_points=input_points, + input_labels=input_labels, + input_boxes=input_boxes, + input_masks=input_masks, + ) + low_res_multimasks, iou_scores, _, object_score_logits = self.mask_decoder( + image_embeddings=image_embeddings[-1], + image_positional_embeddings=image_positional_embeddings, + sparse_prompt_embeddings=sparse_embeddings, + dense_prompt_embeddings=dense_embeddings, + multimask_output=multimask_output, + high_resolution_features=image_embeddings[:-1], + attention_similarity=attention_similarity, + target_embedding=target_embedding, + **kwargs, + ) + + return Sam3TrackerImageSegmentationOutput( + iou_scores=iou_scores, + pred_masks=low_res_multimasks, + object_score_logits=object_score_logits, + image_embeddings=image_embeddings, + vision_hidden_states=vision_hidden_states, + vision_attentions=vision_attentions, + ) + + @can_return_tuple + @auto_docstring + def get_image_features( + self, + pixel_values: torch.FloatTensor, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple | Sam3TrackerVisionEncoderOutput: + r""" + pixel_values (`torch.FloatTensor`): + Input pixel values of shape `(batch_size, num_channels, height, width)`. + """ + vision_outputs: Sam3TrackerVisionEncoderOutput = self.vision_encoder(pixel_values, return_dict=True, **kwargs) + + feature_maps = vision_outputs.fpn_hidden_states + feature_maps_position_embeddings = vision_outputs.fpn_position_encoding + + # precompute projected level 0 and level 1 features in SAM decoder + # to avoid running it again on every SAM click + feature_maps = list(feature_maps) + feature_maps[0] = self.mask_decoder.conv_s0(feature_maps[0]) + feature_maps[1] = self.mask_decoder.conv_s1(feature_maps[1]) + + # flatten NxCxHxW to HWxNxC + feature_maps = [feature_map.flatten(2).permute(2, 0, 1) for feature_map in feature_maps] + feature_maps_position_embeddings = [ + feature_map_position_embedding.flatten(2).permute(2, 0, 1) + for feature_map_position_embedding in feature_maps_position_embeddings + ] + vision_outputs.fpn_hidden_states = feature_maps + vision_outputs.fpn_position_encoding = feature_maps_position_embeddings + + return vision_outputs + + +__all__ = ["Sam3TrackerModel", "Sam3TrackerPreTrainedModel"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam3_tracker/modular_sam3_tracker.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam3_tracker/modular_sam3_tracker.py new file mode 100644 index 0000000000000000000000000000000000000000..74d6e5a50f839a15af4d473b7fd6c687715e2071 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam3_tracker/modular_sam3_tracker.py @@ -0,0 +1,288 @@ +# Copyright 2025 the HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import torch + +from ... import initialization as init +from ...configuration_utils import PreTrainedConfig +from ...modeling_utils import PreTrainedModel +from ...utils import auto_docstring +from ..auto import CONFIG_MAPPING, AutoModel +from ..sam2.configuration_sam2 import ( + Sam2Config, + Sam2MaskDecoderConfig, + Sam2PromptEncoderConfig, +) +from ..sam2.modeling_sam2 import ( + Sam2Attention, + Sam2FeedForward, + Sam2ImageSegmentationOutput, + Sam2LayerNorm, + Sam2MaskDecoder, + Sam2MaskEmbedding, + Sam2Model, + Sam2PositionalEmbedding, + Sam2PreTrainedModel, + Sam2PromptEncoder, + Sam2TwoWayAttentionBlock, + Sam2TwoWayTransformer, +) +from ..sam2.processing_sam2 import Sam2Processor + + +class Sam3TrackerPromptEncoderConfig(Sam2PromptEncoderConfig): + r""" + This is the configuration class to store the configuration of a [`Sam3TrackerPromptEncoder`]. The [`Sam3TrackerPromptEncoder`] + module is used to encode the input 2D points and bounding boxes. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + hidden_size (`int`, *optional*, defaults to 256): + Dimensionality of the hidden states. + image_size (`int`, *optional*, defaults to 1008): + The expected output resolution of the image. + patch_size (`int`, *optional*, defaults to 14): + The size (resolution) of each patch. + mask_input_channels (`int`, *optional*, defaults to 16): + The number of channels to be fed to the `MaskDecoder` module. + num_point_embeddings (`int`, *optional*, defaults to 4): + The number of point embeddings to be used. + hidden_act (`str`, *optional*, defaults to `"gelu"`): + The non-linear activation function in the encoder and pooler. + layer_norm_eps (`float`, *optional*, defaults to 1e-06): + The epsilon used by the layer normalization layers. + scale (`float`, *optional*, defaults to 1): + The scale factor for the prompt encoder. + """ + + base_config_key = "prompt_encoder_config" + + def __init__( + self, + hidden_size=256, + image_size=1008, + patch_size=14, + mask_input_channels=16, + num_point_embeddings=4, + hidden_act="gelu", + layer_norm_eps=1e-6, + scale=1, + **kwargs, + ): + super().__init__(**kwargs) + + +class Sam3TrackerProcessor(Sam2Processor): + pass + + +class Sam3TrackerMaskDecoderConfig(Sam2MaskDecoderConfig): + pass + + +class Sam3TrackerConfig(Sam2Config): + r""" + [`Sam3TrackerConfig`] is the configuration class to store the configuration of a [`Sam3TrackerModel`]. It is used to instantiate a + SAM3_TRACKER model according to the specified arguments, defining the memory attention, memory encoder, and image encoder + configs. Instantiating a configuration defaults will yield a similar configuration to that of the SAM 2.1 Hiera-tiny + [facebook/sam3_tracker.1-hiera-tiny](https://huggingface.co/facebook/sam3_tracker.1-hiera-tiny) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + + + SAM3 Tracker checkpoints with `model_type="sam3_tracker_video"` are compatible with `Sam3TrackerModel` since the + video variant weights are a superset of the image-only model weights. You may see a warning about model type + mismatch when loading such checkpoints, which can be safely ignored in this case. + + + + Args: + vision_config (Union[`dict`, `Sam3TrackerVisionConfig`], *optional*): + Dictionary of configuration options used to initialize [`Sam3TrackerVisionConfig`]. + prompt_encoder_config (Union[`dict`, `Sam3TrackerPromptEncoderConfig`], *optional*): + Dictionary of configuration options used to initialize [`Sam3TrackerPromptEncoderConfig`]. + mask_decoder_config (Union[`dict`, `Sam3TrackerMaskDecoderConfig`], *optional*): + Dictionary of configuration options used to initialize [`Sam3TrackerMaskDecoderConfig`]. + initializer_range (`float`, *optional*, defaults to 0.02): + Standard deviation for parameter initialization. + + Example: + + ```python + >>> from transformers import ( + ... Sam3TrackerVisionConfig, + ... Sam3TrackerPromptEncoderConfig, + ... Sam3TrackerMaskDecoderConfig, + ... Sam3TrackerModel, + ... ) + + >>> # Initializing a Sam3TrackerConfig with `"facebook/sam3_tracker.1_hiera_tiny"` style configuration + >>> configuration = Sam3TrackerConfig() + + >>> # Initializing a Sam3TrackerModel (with random weights) from the `"facebook/sam3_tracker.1_hiera_tiny"` style configuration + >>> model = Sam3TrackerModel(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + + >>> # We can also initialize a Sam3TrackerConfig from a Sam3TrackerVisionConfig, Sam3TrackerPromptEncoderConfig, and Sam3TrackerMaskDecoderConfig + >>> # Initializing SAM3_TRACKER vision encoder, memory attention, and memory encoder configurations + >>> vision_config = Sam3TrackerVisionConfig() + >>> prompt_encoder_config = Sam3TrackerPromptEncoderConfig() + >>> mask_decoder_config = Sam3TrackerMaskDecoderConfig() + + >>> config = Sam3TrackerConfig(vision_config, prompt_encoder_config, mask_decoder_config) + ``` + """ + + def __init__( + self, + vision_config=None, + prompt_encoder_config=None, + mask_decoder_config=None, + initializer_range=0.02, + **kwargs, + ): + vision_config = ( + vision_config + if vision_config is not None + else {"backbone_feature_sizes": [[288, 288], [144, 144], [72, 72]]} + ) + prompt_encoder_config = prompt_encoder_config if prompt_encoder_config is not None else {} + mask_decoder_config = mask_decoder_config if mask_decoder_config is not None else {} + + if isinstance(vision_config, dict): + vision_config["model_type"] = vision_config.get("model_type", "sam3_vision_model") + vision_config = CONFIG_MAPPING[vision_config["model_type"]](**vision_config) + if isinstance(prompt_encoder_config, Sam3TrackerPromptEncoderConfig): + prompt_encoder_config = prompt_encoder_config.to_dict() + if isinstance(mask_decoder_config, Sam3TrackerMaskDecoderConfig): + mask_decoder_config = mask_decoder_config.to_dict() + + self.vision_config = vision_config + self.prompt_encoder_config = Sam3TrackerPromptEncoderConfig(**prompt_encoder_config) + self.mask_decoder_config = Sam3TrackerMaskDecoderConfig(**mask_decoder_config) + + self.initializer_range = initializer_range + PreTrainedConfig.__init__(**kwargs) + + +class Sam3TrackerImageSegmentationOutput(Sam2ImageSegmentationOutput): + pass + + +class Sam3TrackerFeedForward(Sam2FeedForward): + pass + + +@auto_docstring( + custom_intro=""" + Segment Anything Model 3 (SAM 3) for generating segmentation masks, given an input image and + input points and labels, boxes, or masks. + """ +) +class Sam3TrackerPreTrainedModel(Sam2PreTrainedModel): + @torch.no_grad() + def _init_weights(self, module): + PreTrainedModel._init_weights(module) + if isinstance(module, Sam3TrackerModel): + if module.no_memory_embedding is not None: + init.zeros_(module.no_memory_embedding) + elif isinstance(module, Sam3TrackerPositionalEmbedding): + init.normal_(module.positional_embedding, std=module.scale) + + +class Sam3TrackerPositionalEmbedding(Sam2PositionalEmbedding): + pass + + +class Sam3TrackerMaskEmbedding(Sam2MaskEmbedding): + pass + + +class Sam3TrackerPromptEncoder(Sam2PromptEncoder): + pass + + +class Sam3TrackerAttention(Sam2Attention): + pass + + +class Sam3TrackerTwoWayAttentionBlock(Sam2TwoWayAttentionBlock): + pass + + +class Sam3TrackerTwoWayTransformer(Sam2TwoWayTransformer): + pass + + +class Sam3TrackerLayerNorm(Sam2LayerNorm): + pass + + +class Sam3TrackerMaskDecoder(Sam2MaskDecoder): + pass + + +class Sam3TrackerModel(Sam2Model): + _checkpoint_conversion_mapping = { + r"tracker_model.(.+)": r"\1", # the regex allows to remove the prefix, and add it back in revert mode + "detector_model.vision_encoder.backbone.": "vision_encoder.backbone.", + "tracker_neck.": "vision_encoder.neck.", + } + _keys_to_ignore_on_load_unexpected = [ + r"^detector_model.", + r"^memory_.*", + r"^mask_downsample.*", + r"^object_pointer_proj.*", + r"^temporal_positional_encoding_projection_layer.*", + "no_memory_positional_encoding", + "no_object_pointer", + "occlusion_spatial_embedding_parameter", + ] + + def __init__(self, config: Sam3TrackerConfig): + # loading from a sam3_video config + if hasattr(config, "tracker_config") and config.tracker_config is not None: + if isinstance(config.tracker_config, dict): + config.tracker_config = Sam3TrackerConfig(**config.tracker_config) + config = config.tracker_config + Sam3TrackerPreTrainedModel.__init__(config) + self.shared_image_embedding = Sam3TrackerPositionalEmbedding(config.prompt_encoder_config) + self.vision_encoder = AutoModel.from_config(config.vision_config) + self.prompt_encoder = Sam3TrackerPromptEncoder(config.prompt_encoder_config) + # The module using it is not a PreTrainedModel subclass so we need this + config.mask_decoder_config._attn_implementation = config._attn_implementation + self.mask_decoder = Sam3TrackerMaskDecoder(config.mask_decoder_config) + + self.backbone_feature_sizes = config.vision_config.backbone_feature_sizes + # a single token to indicate no memory embedding from previous frames + self.hidden_dim = config.vision_config.fpn_hidden_size + self.no_memory_embedding = torch.nn.Parameter(torch.zeros(1, 1, self.hidden_dim)) + + self.post_init() + + +__all__ = [ + "Sam3TrackerConfig", + "Sam3TrackerPromptEncoderConfig", + "Sam3TrackerMaskDecoderConfig", + "Sam3TrackerProcessor", + "Sam3TrackerModel", + "Sam3TrackerPreTrainedModel", +] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam3_tracker/processing_sam3_tracker.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam3_tracker/processing_sam3_tracker.py new file mode 100644 index 0000000000000000000000000000000000000000..73296fd6c1d4081fcbbd4b673809e9e5ba996fe7 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam3_tracker/processing_sam3_tracker.py @@ -0,0 +1,509 @@ +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# This file was automatically generated from src/transformers/models/sam3_tracker/modular_sam3_tracker.py. +# Do NOT edit this file manually as any edits will be overwritten by the generation of +# the file from the modular. If any change should be done, please apply the change to the +# modular_sam3_tracker.py file directly. One of our CI enforces this. +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# Copyright 2025 the HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +from copy import deepcopy + +import numpy as np +import torch + +from ...image_utils import ImageInput +from ...processing_utils import ProcessorMixin +from ...tokenization_utils_base import BatchEncoding +from ...utils import TensorType, auto_docstring +from ...utils.import_utils import requires + + +@requires(backends=("torch",)) +@auto_docstring +class Sam3TrackerProcessor(ProcessorMixin): + def __init__(self, image_processor, target_size: int | None = None, point_pad_value: int = -10, **kwargs): + r""" + target_size (`int`, *optional*): + The target size (in pixels) for normalizing input points and bounding boxes. If not provided, defaults + to the image processor's size configuration. All input coordinates (points and boxes) are normalized + to this size before being passed to the model. This ensures consistent coordinate representation + regardless of the original image dimensions. + point_pad_value (`int`, *optional*, defaults to -10): + The value used for padding input points when batching sequences of different lengths. This value is + used to mark padded positions and is preserved during coordinate normalization. + """ + super().__init__(image_processor, **kwargs) + self.point_pad_value = point_pad_value + self.target_size = target_size if target_size is not None else self.image_processor.size["height"] + + @auto_docstring + def __call__( + self, + images: ImageInput | None = None, + segmentation_maps: ImageInput | None = None, + input_points: list[list[list[list[float]]]] | torch.Tensor | None = None, + input_labels: list[list[list[int]]] | torch.Tensor | None = None, + input_boxes: list[list[list[float]]] | torch.Tensor | None = None, + original_sizes: list[list[float]] | torch.Tensor | None = None, + return_tensors: str | TensorType | None = None, + **kwargs, + ) -> BatchEncoding: + r""" + segmentation_maps (`ImageInput`, *optional*): + The segmentation maps to process. + input_points (`list[list[list[list[float]]]]`, `torch.Tensor`, *optional*): + The points to add to the frame. + input_labels (`list[list[list[int]]]`, `torch.Tensor`, *optional*): + The labels for the points. + input_boxes (`list[list[list[float]]]`, `torch.Tensor`, *optional*): + The bounding boxes to add to the frame. + original_sizes (`list[list[float]]`, `torch.Tensor`, *optional*): + The original sizes of the images. + + Returns: + A [`BatchEncoding`] with the following fields: + - `pixel_values` (`torch.Tensor`): The processed image(s). + - `original_sizes` (`list[list[float]]`): The original sizes of the images. + - `labels` (`torch.Tensor`): The processed segmentation maps (if provided). + - `input_points` (`torch.Tensor`): The processed points. + - `input_labels` (`torch.Tensor`): The processed labels. + - `input_boxes` (`torch.Tensor`): The processed bounding boxes. + """ + if images is not None: + encoding_image_processor = self.image_processor( + images, + segmentation_maps=segmentation_maps, + return_tensors=return_tensors, + **kwargs, + ) + elif original_sizes is not None: + if isinstance(original_sizes, torch.Tensor): + original_sizes = original_sizes.cpu().tolist() + encoding_image_processor = BatchEncoding({"original_sizes": original_sizes}, tensor_type=return_tensors) + else: + raise ValueError("Either images or original_sizes must be provided") + + # pop arguments that are not used in the forward but used nevertheless + original_sizes = encoding_image_processor["original_sizes"] + # Check original_sizes is of length 1 or len(images) + if images is not None and len(original_sizes) != 1 and len(original_sizes) != len(images): + raise ValueError( + "original_sizes must be of length 1 or len(images). If you are passing a single image, you must pass a single original_size." + ) + + # Process input points, labels, and boxes if provided + if input_points is not None or input_labels is not None or input_boxes is not None: + # Validate and convert inputs to standardized format + processed_points = self._validate_single_input( + input_points, + expected_depth=4, + input_name="points", + expected_format="[image level, object level, point level, point coordinates]", + expected_coord_size=2, + ) + processed_labels = self._validate_single_input( + input_labels, + expected_depth=3, + input_name="labels", + expected_format="[image level, object level, point level]", + ) + processed_boxes = self._validate_single_input( + input_boxes, + expected_depth=3, + input_name="boxes", + expected_format="[image level, box level, box coordinates]", + expected_coord_size=4, + ) + + # Get padding requirements for all inputs + if processed_points is not None: + points_max_dims = self._get_nested_dimensions(processed_points)[:3] + if processed_labels is not None: + labels_max_dims = self._get_nested_dimensions(processed_labels)[:3] + if processed_boxes is not None: + boxes_max_dims = self._get_nested_dimensions(processed_boxes)[:2] + + # Ensure points and labels have consistent dimensions + if processed_points is not None and processed_labels is not None: + if points_max_dims != labels_max_dims: + raise ValueError( + "Input points and labels have inconsistent dimensions. Please ensure they have the same dimensions." + ) + + # Check that boxes don't need padding (model limitation) + if processed_boxes is not None and len(processed_boxes) >= 2: + if any(len(img_boxes) < boxes_max_dims[1] for img_boxes in processed_boxes): + raise ValueError( + "Input boxes have inconsistent dimensions that would require padding, " + "but boxes cannot be padded due to model limitations. " + "Please ensure all images have the same number of boxes." + ) + + # Pad and normalize all inputs to final tensor format + if processed_points is not None: + padded_points = self._pad_nested_list(processed_points, points_max_dims + [2]) + final_points = torch.tensor(padded_points, dtype=torch.float32) + self._normalize_tensor_coordinates(final_points, original_sizes, preserve_padding=True) + encoding_image_processor.update({"input_points": final_points}) + + if processed_labels is not None: + padded_labels = self._pad_nested_list(processed_labels, labels_max_dims) + final_labels = torch.tensor(padded_labels, dtype=torch.int64) + encoding_image_processor.update({"input_labels": final_labels}) + + if processed_boxes is not None: + final_boxes = torch.tensor(processed_boxes, dtype=torch.float32) + self._normalize_tensor_coordinates(final_boxes, original_sizes, is_bounding_box=True) + encoding_image_processor.update({"input_boxes": final_boxes}) + + return encoding_image_processor + + def _normalize_coordinates( + self, target_size: int, coords: "torch.Tensor", original_size, is_bounding_box=False + ) -> "torch.Tensor": + """ + Expects a numpy array of length 2 in the final dimension. Requires the original image size in (H, W) format. + + Args: + target_size (`int`): + The target size of the image. + coords (`torch.Tensor`): + The coordinates to be normalized. + original_size (`tuple`): + The original size of the image. + is_bounding_box (`bool`, *optional*, defaults to `False`): + Whether the coordinates are bounding boxes. + """ + old_h, old_w = original_size + new_h, new_w = target_size, target_size + coords = deepcopy(coords).float() + + if is_bounding_box: + coords = coords.reshape(-1, 2, 2) + coords[..., 0] = coords[..., 0] * (new_w / old_w) + coords[..., 1] = coords[..., 1] * (new_h / old_h) + + if is_bounding_box: + coords = coords.reshape(-1, 4) + + return coords + + def _convert_to_nested_list(self, data, expected_depth, current_depth=0): + """ + Recursively convert various input formats (tensors, numpy arrays, lists) to nested lists. + + Args: + data: Input data in any format + expected_depth: Expected nesting depth + current_depth: Current depth in recursion + + Returns: + Nested list representation of the data + """ + if data is None: + return None + + # Convert tensor/numpy to list if we're at a leaf level or if it's a multi-dimensional array + if isinstance(data, torch.Tensor): # PyTorch tensor + if current_depth == expected_depth - 2 or len(data.shape) <= 2: # At coordinate level or small tensor + return data.numpy().tolist() + else: + return [self._convert_to_nested_list(item, expected_depth, current_depth + 1) for item in data] + elif isinstance(data, np.ndarray): # NumPy array + if current_depth == expected_depth - 2 or len(data.shape) <= 2: # At coordinate level or small array + return data.tolist() + else: + return [self._convert_to_nested_list(item, expected_depth, current_depth + 1) for item in data] + elif isinstance(data, list): + if current_depth == expected_depth: + # We've reached the expected depth, return as is + return data + else: + # Continue recursion + return [self._convert_to_nested_list(item, expected_depth, current_depth + 1) for item in data] + elif isinstance(data, (int, float)): + return data + else: + raise TypeError(f"Unsupported data type: {type(data)}") + + def _get_nested_dimensions(self, nested_list, max_dims=None): + """ + Get the maximum dimensions at each level of nesting. + + Args: + nested_list (`list`): + Nested list structure. + max_dims (`list`, *optional*): + Current maximum dimensions (for recursion). + + Returns: + `list`: A list of maximum dimensions for each nesting level. + """ + if max_dims is None: + max_dims = [] + + if not isinstance(nested_list, list): + return max_dims + + if len(max_dims) == 0: + max_dims.append(len(nested_list)) + else: + max_dims[0] = max(max_dims[0], len(nested_list)) + + if len(nested_list) > 0: + for item in nested_list: + if isinstance(item, list): + sub_dims = self._get_nested_dimensions(item) + # Merge sub_dims into max_dims + for i, dim in enumerate(sub_dims): + if i + 1 >= len(max_dims): + max_dims.append(dim) + else: + max_dims[i + 1] = max(max_dims[i + 1], dim) + + return max_dims + + def _pad_nested_list(self, nested_list, target_dims, current_level=0, pad_value=None): + """ + Recursively pad a nested list to match target dimensions. + + Args: + nested_list (`list`): + Nested list to pad. + target_dims (`list`): + Target dimensions for each level. + current_level (`int`, *optional*, defaults to 0): + Current nesting level. + pad_value (`int`, *optional*): + Value to use for padding. + + Returns: + `list`: The padded nested list. + """ + if pad_value is None: + pad_value = self.point_pad_value + + if current_level >= len(target_dims): + return nested_list + + # Ensure we have a list + if not isinstance(nested_list, list): + nested_list = [nested_list] + + # Pad current level + current_size = len(nested_list) + target_size = target_dims[current_level] + + # Pad with appropriate values + if current_level == len(target_dims) - 1: + # At the coordinate level, pad with pad_value + nested_list.extend([pad_value] * (target_size - current_size)) + else: + # At higher levels, pad with nested structures + if current_size > 0: + # Create appropriately sized template + if current_level < len(target_dims) - 2: + # For non-coordinate levels, create empty nested structure + template_dims = target_dims[current_level + 1 :] + template = self._create_empty_nested_structure(template_dims, pad_value) + else: + # For coordinate level, create list of pad_values + template = [pad_value] * target_dims[current_level + 1] + + nested_list.extend([deepcopy(template) for _ in range(target_size - current_size)]) + else: + # Create from scratch + template_dims = target_dims[current_level + 1 :] + template = self._create_empty_nested_structure(template_dims, pad_value) + nested_list.extend([deepcopy(template) for _ in range(target_size)]) + + # Recursively pad sublists + if current_level < len(target_dims) - 1: + for i in range(len(nested_list)): + if isinstance(nested_list[i], list): + nested_list[i] = self._pad_nested_list(nested_list[i], target_dims, current_level + 1, pad_value) + + return nested_list + + def _create_empty_nested_structure(self, dims, pad_value): + """ + Create an empty nested structure with given dimensions filled with pad_value. + + Args: + dims (`list`): + The dimensions of the nested structure. + pad_value (`int`): + The value to fill the structure with. + """ + if len(dims) == 1: + return [pad_value] * dims[0] + else: + return [self._create_empty_nested_structure(dims[1:], pad_value) for _ in range(dims[0])] + + def _get_nesting_level(self, input_list): + """ + Get the nesting level of a list structure. + + Args: + input_list (`list`): + The list to get the nesting level of. + """ + if isinstance(input_list, list): + if len(input_list) == 0: + return 1 + return 1 + self._get_nesting_level(input_list[0]) + elif isinstance(input_list, (np.ndarray, torch.Tensor)): + # For arrays/tensors, the nesting level is the number of dimensions + return len(input_list.shape) + return 0 + + def _validate_single_input( + self, + data: torch.Tensor | np.ndarray | list, + expected_depth: int, + input_name: str, + expected_format: str, + expected_coord_size: int | None = None, + ) -> list: + """ + Validate a single input by ensuring proper nesting and raising an error if the input is not valid. + + Args: + data (`torch.Tensor`, `np.ndarray`, or `list`): + Input data to process. + expected_depth (`int`): + Expected nesting depth. + input_name (`str`): + Name of the input for error messages. + expected_format (`str`): + The expected format of the input. + expected_coord_size (`int`, *optional*): + Expected coordinate size (2 for points, 4 for boxes, None for labels). + . + """ + if data is None: + return None + + # Handle tensors and numpy arrays first + if isinstance(data, (torch.Tensor, np.ndarray)): + # For tensors/arrays, we can directly check the number of dimensions + if data.ndim != expected_depth: + raise ValueError( + f"Input {input_name} must be a tensor/array with {expected_depth} dimensions. The expected nesting format is {expected_format}. Got {data.ndim} dimensions." + ) + elif expected_coord_size is not None: + if data.shape[-1] != expected_coord_size: + raise ValueError( + f"Input {input_name} must be a tensor/array with {expected_coord_size} as the last dimension, got {data.shape[-1]}." + ) + return self._convert_to_nested_list(data, expected_depth) + + # Handle nested lists + if isinstance(data, list): + current_depth = self._get_nesting_level(data) + if current_depth != expected_depth: + raise ValueError( + f"Input {input_name} must be a nested list with {expected_depth} levels. The expected nesting format is {expected_format}. Got {current_depth} levels." + ) + return self._convert_to_nested_list(data, expected_depth) + + def _normalize_tensor_coordinates(self, tensor, original_sizes, is_bounding_box=False, preserve_padding=False): + """ + Helper method to normalize coordinates in a tensor across multiple images. + + Args: + tensor (`torch.Tensor`): + Input tensor with coordinates. + original_sizes (`list`): + Original image sizes. + is_bounding_box (`bool`, *optional*, defaults to `False`): + Whether coordinates are bounding boxes. + preserve_padding (`bool`, *optional*, defaults to `False`): + Whether to preserve padding values (for points). + """ + if preserve_padding: + # For points: avoid normalizing pad values + mask = tensor != self.point_pad_value + coord_mask = mask.all(dim=-1, keepdim=True) + + for img_idx in range(len(original_sizes)): + if img_idx < tensor.shape[0]: + original_size = original_sizes[img_idx] if img_idx < len(original_sizes) else original_sizes[0] + normalized_coords = self._normalize_coordinates( + self.target_size, tensor[img_idx], original_size, is_bounding_box=is_bounding_box + ) + + if preserve_padding: + # Only update non-padded values + img_mask = coord_mask[img_idx] + tensor[img_idx] = torch.where( + img_mask.expand_as(tensor[img_idx]), normalized_coords, tensor[img_idx] + ) + else: + tensor[img_idx] = normalized_coords + + def post_process_masks( + self, + masks, + original_sizes, + mask_threshold=0.0, + binarize=True, + max_hole_area=0.0, + max_sprinkle_area=0.0, + apply_non_overlapping_constraints=False, + **kwargs, + ): + """ + Remove padding and upscale masks to the original image size. + + Args: + masks (`Union[List[torch.Tensor], List[np.ndarray]]`): + Batched masks from the mask_decoder in (batch_size, num_channels, height, width) format. + original_sizes (`Union[torch.Tensor, List[Tuple[int,int]]]`): + The original sizes of each image before it was resized to the model's expected input shape, in (height, + width) format. + mask_threshold (`float`, *optional*, defaults to 0.0): + Threshold for binarization and post-processing operations. + binarize (`bool`, *optional*, defaults to `True`): + Whether to binarize the masks. + max_hole_area (`float`, *optional*, defaults to 0.0): + The maximum area of a hole to fill. + max_sprinkle_area (`float`, *optional*, defaults to 0.0): + The maximum area of a sprinkle to fill. + apply_non_overlapping_constraints (`bool`, *optional*, defaults to `False`): + Whether to apply non-overlapping constraints to the masks. + + Returns: + (`torch.Tensor`): Batched masks in batch_size, num_channels, height, width) format, where (height, width) + is given by original_size. + """ + return self.image_processor.post_process_masks( + masks, + original_sizes, + mask_threshold, + binarize, + max_hole_area, + max_sprinkle_area, + apply_non_overlapping_constraints, + **kwargs, + ) + + @property + def model_input_names(self): + image_processor_input_names = self.image_processor.model_input_names + return list(image_processor_input_names + ["original_sizes"]) + + +__all__ = ["Sam3TrackerProcessor"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam3_tracker_video/__init__.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam3_tracker_video/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..864afc45a4ef233dc76c32dd835a6a7fabdfe181 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam3_tracker_video/__init__.py @@ -0,0 +1,29 @@ +# Copyright 2025 the HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +from typing import TYPE_CHECKING + +from ...utils import _LazyModule +from ...utils.import_utils import define_import_structure + + +if TYPE_CHECKING: + from .configuration_sam3_tracker_video import * + from .modeling_sam3_tracker_video import * + from .processing_sam3_tracker_video import * +else: + import sys + + _file = globals()["__file__"] + sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__) diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam3_tracker_video/configuration_sam3_tracker_video.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam3_tracker_video/configuration_sam3_tracker_video.py new file mode 100644 index 0000000000000000000000000000000000000000..946ac3732df0108da0fc5e9cfbed263637067e7b --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam3_tracker_video/configuration_sam3_tracker_video.py @@ -0,0 +1,425 @@ +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# This file was automatically generated from src/transformers/models/sam3_tracker_video/modular_sam3_tracker_video.py. +# Do NOT edit this file manually as any edits will be overwritten by the generation of +# the file from the modular. If any change should be done, please apply the change to the +# modular_sam3_tracker_video.py file directly. One of our CI enforces this. +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# Copyright 2025 the HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + + +from ...configuration_utils import PreTrainedConfig +from ..auto import CONFIG_MAPPING, AutoConfig + + +class Sam3TrackerVideoPromptEncoderConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`Sam3TrackerVideoPromptEncoder`]. The [`Sam3TrackerVideoPromptEncoder`] + module is used to encode the input 2D points and bounding boxes. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + hidden_size (`int`, *optional*, defaults to 256): + Dimensionality of the hidden states. + image_size (`int`, *optional*, defaults to 1008): + The expected output resolution of the image. + patch_size (`int`, *optional*, defaults to 14): + The size (resolution) of each patch. + mask_input_channels (`int`, *optional*, defaults to 16): + The number of channels to be fed to the `MaskDecoder` module. + num_point_embeddings (`int`, *optional*, defaults to 4): + The number of point embeddings to be used. + hidden_act (`str`, *optional*, defaults to `"gelu"`): + The non-linear activation function in the encoder and pooler. + layer_norm_eps (`float`, *optional*, defaults to 1e-06): + The epsilon used by the layer normalization layers. + scale (`float`, *optional*, defaults to 1): + The scale factor for the prompt encoder. + """ + + base_config_key = "prompt_encoder_config" + + def __init__( + self, + hidden_size=256, + image_size=1008, + patch_size=14, + mask_input_channels=16, + num_point_embeddings=4, + hidden_act="gelu", + layer_norm_eps=1e-6, + scale=1, + **kwargs, + ): + super().__init__(**kwargs) + self.hidden_size = hidden_size + self.image_size = image_size + self.patch_size = patch_size + self.mask_input_channels = mask_input_channels + self.num_point_embeddings = num_point_embeddings + self.hidden_act = hidden_act + self.layer_norm_eps = layer_norm_eps + self.scale = scale + + +class Sam3TrackerVideoMaskDecoderConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`Sam3TrackerVideoMaskDecoder`]. It is used to instantiate a SAM3_TRACKER_VIDEO + memory encoder according to the specified arguments, defining the model architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + hidden_size (`int`, *optional*, defaults to 256): + Dimensionality of the hidden states. + hidden_act (`str`, *optional*, defaults to `"gelu"`): + The non-linear activation function in the SAM3_TRACKER_VIDEO mask decoder. + mlp_dim (`int`, *optional*, defaults to 2048): + The dimension of the MLP in the two-way transformer. + num_hidden_layers (`int`, *optional*, defaults to 2): + The number of hidden layers in the two-way transformer. + num_attention_heads (`int`, *optional*, defaults to 8): + The number of attention heads in the two-way transformer. + attention_downsample_rate (`int`, *optional*, defaults to 2): + The downsample rate for the attention layers. + num_multimask_outputs (`int`, *optional*, defaults to 3): + The number of multimask outputs. + iou_head_depth (`int`, *optional*, defaults to 3): + The depth of the IoU head. + iou_head_hidden_dim (`int`, *optional*, defaults to 256): + The hidden dimension of the IoU head. + dynamic_multimask_via_stability (`bool`, *optional*, defaults to `True`): + Whether to use dynamic multimask via stability. + dynamic_multimask_stability_delta (`float`, *optional*, defaults to 0.05): + The stability delta for the dynamic multimask. + dynamic_multimask_stability_thresh (`float`, *optional*, defaults to 0.98): + The stability threshold for the dynamic multimask. + + """ + + base_config_key = "mask_decoder_config" + + def __init__( + self, + hidden_size=256, + hidden_act="gelu", + mlp_dim=2048, + num_hidden_layers=2, + num_attention_heads=8, + attention_downsample_rate=2, + num_multimask_outputs=3, + iou_head_depth=3, + iou_head_hidden_dim=256, + dynamic_multimask_via_stability=True, + dynamic_multimask_stability_delta=0.05, + dynamic_multimask_stability_thresh=0.98, + **kwargs, + ): + super().__init__(**kwargs) + + self.hidden_size = hidden_size + self.num_multimask_outputs = num_multimask_outputs + self.hidden_act = hidden_act + self.iou_head_depth = iou_head_depth + self.iou_head_hidden_dim = iou_head_hidden_dim + self.dynamic_multimask_via_stability = dynamic_multimask_via_stability + self.dynamic_multimask_stability_delta = dynamic_multimask_stability_delta + self.dynamic_multimask_stability_thresh = dynamic_multimask_stability_thresh + + # TwoWayTransformer configuration + self.num_hidden_layers = num_hidden_layers + self.hidden_size = hidden_size + self.num_attention_heads = num_attention_heads + self.mlp_dim = mlp_dim + self.attention_downsample_rate = attention_downsample_rate + + +class Sam3TrackerVideoConfig(PreTrainedConfig): + r""" + [`Sam3TrackerVideoConfig`] is the configuration class to store the configuration of a [`Sam3TrackerVideoModel`]. It is used to instantiate a + SAM3 tracker video model according to the specified arguments, defining the memory attention, memory encoder, and image encoder + configs. Instantiating a configuration defaults will yield a similar configuration to that of the SAM 3 + [facebook/sam3](https://huggingface.co/facebook/sam3) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + vision_config (Union[`dict`, `Sam3TrackerVideoVisionConfig`], *optional*): + Dictionary of configuration options used to initialize [`Sam3TrackerVideoVisionConfig`]. + prompt_encoder_config (Union[`dict`, `Sam3TrackerVideoPromptEncoderConfig`], *optional*): + Dictionary of configuration options used to initialize [`Sam3TrackerVideoPromptEncoderConfig`]. + mask_decoder_config (Union[`dict`, `Sam3TrackerVideoMaskDecoderConfig`], *optional*): + Dictionary of configuration options used to initialize [`Sam3TrackerVideoMaskDecoderConfig`]. + initializer_range (`float`, *optional*, defaults to 0.02): + Standard deviation for parameter initialization. + num_maskmem (`int`, *optional*, defaults to 7): + The number of memory slots for the mask memory. + image_size (`int`, *optional*, defaults to 1008): + The size of the input images. + sigmoid_scale_for_mem_enc (`float`, *optional*, defaults to 20.0): + Scale factor for the sigmoid function in the memory encoder. + sigmoid_bias_for_mem_enc (`float`, *optional*, defaults to -10.0): + Bias for the sigmoid function in the memory encoder. + enable_occlusion_spatial_embedding (`bool`, *optional*, defaults to `True`): + Whether to enable spatial embedding for occlusions. + multimask_output_in_sam (`bool`, *optional*, defaults to `True`): + Whether to output multiple masks from the SAM head. + multimask_min_pt_num (`int`, *optional*, defaults to 0): + The minimum number of points to trigger multimask output. + multimask_max_pt_num (`int`, *optional*, defaults to 1): + The maximum number of points to trigger multimask output. + multimask_output_for_tracking (`bool`, *optional*, defaults to `True`): + Whether to use multimask output for tracking. + max_object_pointers_in_encoder (`int`, *optional*, defaults to 16): + The maximum number of object pointers in the encoder. + max_cond_frame_num (`int`, *optional*, defaults to 4): + Maximum number of conditioning frames to use in memory attention. + enable_temporal_pos_encoding_for_object_pointers (`bool`, *optional*, defaults to `True`): + Whether to enable temporal positional encoding for object pointers. + memory_attention_hidden_size (`int`, *optional*, defaults to 256): + Dimensionality of the memory attention hidden states. + memory_attention_num_layers (`int`, *optional*, defaults to 4): + The number of layers in the memory attention module. + memory_attention_num_attention_heads (`int`, *optional*, defaults to 1): + Number of attention heads for each attention layer in the memory attention. + memory_attention_downsample_rate (`int`, *optional*, defaults to 1): + The downsample rate for the attention layers. + memory_attention_feed_forward_hidden_size (`int`, *optional*, defaults to 2048): + The dimension of the feedforward network in the memory attention module. + memory_attention_feed_forward_hidden_act (`str`, *optional*, defaults to `"relu"`): + The non-linear activation function in the feedforward network in the memory attention module. + memory_attention_dropout (`float`, *optional*, defaults to 0.1): + The dropout rate for the memory attention module. + memory_attention_rope_theta (`float`, *optional*, defaults to 10000): + The Rope theta parameter. + memory_attention_rope_feat_sizes (`list[int]`, *optional*, defaults to `[72, 72]`): + The feature sizes for the Rope positional encoding. + memory_attention_rope_dropout (`float`, *optional*, defaults to 0.1): + The dropout rate for the Rope positional encoding. + memory_encoder_hidden_size (`int`, *optional*, defaults to 256): + Dimensionality of the memory encoder hidden states. + memory_encoder_output_channels (`int`, *optional*, defaults to 64): + The number of output channels for the memory encoder. + mask_downsampler_embed_dim (`int`, *optional*, defaults to 256): + The dimension of the mask downsampler embedding. + mask_downsampler_kernel_size (`int`, *optional*, defaults to 3): + The kernel size for the mask downsampler. + mask_downsampler_stride (`int`, *optional*, defaults to 2): + The stride for the mask downsampler. + mask_downsampler_padding (`int`, *optional*, defaults to 1): + The padding for the mask downsampler. + mask_downsampler_total_stride (`int`, *optional*, defaults to 16): + The total stride for the mask downsampler. + mask_downsampler_hidden_act (`str`, *optional*, defaults to `"gelu"`): + The non-linear activation function in the mask downsampler. + memory_fuser_num_layers (`int`, *optional*, defaults to 2): + The number of layers in the memory fuser. + memory_fuser_embed_dim (`int`, *optional*, defaults to 256): + The dimension of the embedding layer in the memory fuser. + memory_fuser_intermediate_dim (`int`, *optional*, defaults to 1024): + The dimension of the intermediate layer in the memory fuser. + memory_fuser_kernel_size (`int`, *optional*, defaults to 7): + The kernel size for the memory fuser. + memory_fuser_padding (`int`, *optional*, defaults to 3): + The padding for the memory fuser. + memory_fuser_layer_scale_init_value (`float`, *optional*, defaults to 1e-06): + The initial value for the layer scale in the memory fuser. + memory_fuser_hidden_act (`str`, *optional*, defaults to `"gelu"`): + The non-linear activation function in the memory fuser. + kwargs (*optional*): + Dictionary of keyword arguments. + + Example: + + ```python + >>> from transformers import ( + ... Sam3VisionConfig, + ... Sam3TrackerVideoPromptEncoderConfig, + ... Sam3TrackerVideoMaskDecoderConfig, + ... Sam3TrackerVideoModel, + ... ) + + >>> # Initializing a Sam3TrackerVideoConfig with `"facebook/sam3"` style configuration + >>> configuration = Sam3TrackerVideoConfig() + + >>> # Initializing a Sam3TrackerVideoModel (with random weights) from the `"facebook/sam3"` style configuration + >>> model = Sam3TrackerVideoModel(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + + >>> # We can also initialize a Sam3TrackerVideoConfig from a Sam3TrackerVideoVisionConfig, Sam3TrackerVideoPromptEncoderConfig, and Sam3TrackerVideoMaskDecoderConfig + + >>> # Initializing SAM3 tracker video vision encoder, memory attention, and memory encoder configurations + >>> vision_config = Sam3TrackerVideoVisionConfig() + >>> prompt_encoder_config = Sam3TrackerVideoPromptEncoderConfig() + >>> mask_decoder_config = Sam3TrackerVideoMaskDecoderConfig() + + >>> config = Sam3TrackerVideoConfig(vision_config, prompt_encoder_config, mask_decoder_config) + ```""" + + model_type = "sam3_tracker_video" + sub_configs = { + "vision_config": AutoConfig, + "prompt_encoder_config": Sam3TrackerVideoPromptEncoderConfig, + "mask_decoder_config": Sam3TrackerVideoMaskDecoderConfig, + } + + def __init__( + self, + vision_config=None, + prompt_encoder_config=None, + mask_decoder_config=None, + initializer_range=0.02, + num_maskmem=7, + image_size=1008, + sigmoid_scale_for_mem_enc=20.0, + sigmoid_bias_for_mem_enc=-10.0, + enable_occlusion_spatial_embedding=True, + multimask_output_in_sam=True, + multimask_min_pt_num=0, + multimask_max_pt_num=1, + multimask_output_for_tracking=True, + max_object_pointers_in_encoder=16, + max_cond_frame_num=4, + enable_temporal_pos_encoding_for_object_pointers=True, + # memory attention + memory_attention_hidden_size=256, + memory_attention_num_layers=4, + memory_attention_num_attention_heads=1, + memory_attention_downsample_rate=1, + memory_attention_feed_forward_hidden_size=2048, + memory_attention_feed_forward_hidden_act="relu", + memory_attention_dropout=0.1, + memory_attention_rope_theta=10000, + memory_attention_rope_feat_sizes=None, + memory_attention_rope_dropout=0.1, + # memory encoder + memory_encoder_hidden_size=256, + memory_encoder_output_channels=64, + mask_downsampler_embed_dim=256, + mask_downsampler_kernel_size=3, + mask_downsampler_stride=2, + mask_downsampler_padding=1, + mask_downsampler_total_stride=16, + mask_downsampler_hidden_act="gelu", + memory_fuser_num_layers=2, + memory_fuser_embed_dim=256, + memory_fuser_intermediate_dim=1024, + memory_fuser_kernel_size=7, + memory_fuser_padding=3, + memory_fuser_layer_scale_init_value=1e-6, + memory_fuser_hidden_act="gelu", + **kwargs, + ): + vision_config = ( + vision_config + if vision_config is not None + else {"backbone_feature_sizes": [[288, 288], [144, 144], [72, 72]]} + ) + prompt_encoder_config = prompt_encoder_config if prompt_encoder_config is not None else {} + mask_decoder_config = mask_decoder_config if mask_decoder_config is not None else {} + memory_attention_rope_feat_sizes = ( + [72, 72] if memory_attention_rope_feat_sizes is None else memory_attention_rope_feat_sizes + ) + + if isinstance(vision_config, dict): + vision_config["model_type"] = vision_config.get("model_type", "sam3_vision_model") + vision_config = CONFIG_MAPPING[vision_config["model_type"]](**vision_config) + if isinstance(prompt_encoder_config, Sam3TrackerVideoPromptEncoderConfig): + prompt_encoder_config = prompt_encoder_config.to_dict() + if isinstance(mask_decoder_config, Sam3TrackerVideoMaskDecoderConfig): + mask_decoder_config = mask_decoder_config.to_dict() + + self.vision_config = vision_config + self.prompt_encoder_config = Sam3TrackerVideoPromptEncoderConfig(**prompt_encoder_config) + self.mask_decoder_config = Sam3TrackerVideoMaskDecoderConfig(**mask_decoder_config) + + self.initializer_range = initializer_range + self.num_maskmem = num_maskmem # default 1 input frame + 6 previous frames + self.image_size = image_size + self.sigmoid_scale_for_mem_enc = sigmoid_scale_for_mem_enc + self.sigmoid_bias_for_mem_enc = sigmoid_bias_for_mem_enc + self.multimask_output_in_sam = multimask_output_in_sam + self.multimask_min_pt_num = multimask_min_pt_num + self.multimask_max_pt_num = multimask_max_pt_num + self.multimask_output_for_tracking = multimask_output_for_tracking + self.max_object_pointers_in_encoder = max_object_pointers_in_encoder + self.max_cond_frame_num = max_cond_frame_num + # The next 4 are True for sam2.1 and False for sam2 + self.enable_occlusion_spatial_embedding = enable_occlusion_spatial_embedding + self.enable_temporal_pos_encoding_for_object_pointers = enable_temporal_pos_encoding_for_object_pointers + + # memory attention + self.memory_attention_hidden_size = memory_attention_hidden_size + self.memory_attention_num_layers = memory_attention_num_layers + self.memory_attention_num_attention_heads = memory_attention_num_attention_heads + self.memory_attention_downsample_rate = memory_attention_downsample_rate + self.memory_attention_feed_forward_hidden_size = memory_attention_feed_forward_hidden_size + self.memory_attention_feed_forward_hidden_act = memory_attention_feed_forward_hidden_act + self.memory_attention_dropout = memory_attention_dropout + self.memory_attention_rope_theta = memory_attention_rope_theta + self.memory_attention_rope_feat_sizes = memory_attention_rope_feat_sizes + self.memory_attention_rope_dropout = memory_attention_rope_dropout + + # memory encoder + self.memory_encoder_hidden_size = memory_encoder_hidden_size + self.memory_encoder_output_channels = memory_encoder_output_channels + self.mask_downsampler_embed_dim = mask_downsampler_embed_dim + self.mask_downsampler_kernel_size = mask_downsampler_kernel_size + self.mask_downsampler_stride = mask_downsampler_stride + self.mask_downsampler_padding = mask_downsampler_padding + self.mask_downsampler_total_stride = mask_downsampler_total_stride + self.mask_downsampler_hidden_act = mask_downsampler_hidden_act + self.memory_fuser_num_layers = memory_fuser_num_layers + self.memory_fuser_embed_dim = memory_fuser_embed_dim + self.memory_fuser_intermediate_dim = memory_fuser_intermediate_dim + self.memory_fuser_kernel_size = memory_fuser_kernel_size + self.memory_fuser_padding = memory_fuser_padding + self.memory_fuser_layer_scale_init_value = memory_fuser_layer_scale_init_value + self.memory_fuser_hidden_act = memory_fuser_hidden_act + + super().__init__(**kwargs) + + @property + def image_size(self): + """Image size for the tracker video model.""" + return self.vision_config.image_size + + @image_size.setter + def image_size(self, value): + """Set the image size and propagate to sub-configs. Calculates feature sizes based on patch_size.""" + self.prompt_encoder_config.image_size = value + self.vision_config.image_size = value + + patch_size = self.vision_config.backbone_config.patch_size + self.vision_config.backbone_feature_sizes = [ + [4 * value // patch_size, 4 * value // patch_size], + [2 * value // patch_size, 2 * value // patch_size], + [value // patch_size, value // patch_size], + ] + self.memory_attention_rope_feat_sizes = [ + value // patch_size, + value // patch_size, + ] + + # keep the image_size in the __dict__ to save the value in the config file (backward compatibility) + self.__dict__["image_size"] = value + + +__all__ = ["Sam3TrackerVideoMaskDecoderConfig", "Sam3TrackerVideoPromptEncoderConfig", "Sam3TrackerVideoConfig"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam3_tracker_video/modeling_sam3_tracker_video.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam3_tracker_video/modeling_sam3_tracker_video.py new file mode 100644 index 0000000000000000000000000000000000000000..3bd55a0bb0bae356e4349390fc7f89c7da872a80 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam3_tracker_video/modeling_sam3_tracker_video.py @@ -0,0 +1,2820 @@ +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# This file was automatically generated from src/transformers/models/sam3_tracker_video/modular_sam3_tracker_video.py. +# Do NOT edit this file manually as any edits will be overwritten by the generation of +# the file from the modular. If any change should be done, please apply the change to the +# modular_sam3_tracker_video.py file directly. One of our CI enforces this. +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# Copyright 2025 the HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + + +import math +from collections import OrderedDict +from collections.abc import Callable, Iterator +from dataclasses import dataclass +from typing import Any + +import numpy as np +import torch +import torch.nn as nn +import torch.nn.functional as F +from torch import Tensor +from tqdm import tqdm + +from ... import initialization as init +from ...activations import ACT2FN +from ...modeling_flash_attention_utils import FlashAttentionKwargs +from ...modeling_layers import GradientCheckpointingLayer +from ...modeling_outputs import BaseModelOutput, BaseModelOutputWithPooling +from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel +from ...processing_utils import Unpack +from ...pytorch_utils import compile_compatible_method_lru_cache +from ...utils import ModelOutput, TransformersKwargs, auto_docstring, can_return_tuple, logging +from ...utils.generic import is_flash_attention_requested +from ...utils.output_capturing import OutputRecorder +from ..auto import AutoModel +from .configuration_sam3_tracker_video import ( + Sam3TrackerVideoConfig, + Sam3TrackerVideoMaskDecoderConfig, + Sam3TrackerVideoPromptEncoderConfig, +) + + +logger = logging.get_logger(__name__) + + +class Sam3TrackerVideoInferenceCache: + """Cache for vision features and model constants.""" + + def __init__( + self, + inference_device: torch.device | str = "cpu", + inference_state_device: torch.device | str = "cpu", + max_vision_features_cache_size: int = 1, + ): + self.inference_device = inference_device + self.inference_state_device = inference_state_device + self.max_vision_features_cache_size = max_vision_features_cache_size + + self._vision_features = {} + + def cache_vision_features(self, frame_idx: int, features: dict): + """Cache vision features with automatic device management.""" + cached = {} + if len(self._vision_features) >= self.max_vision_features_cache_size: + # remove the oldest frame + self._vision_features.pop(min(self._vision_features.keys())) + + for key, value in features.items(): + if isinstance(value, torch.Tensor): + cached[key] = value.to(self.inference_state_device, non_blocking=True) + elif isinstance(value, (list, tuple)) and value and isinstance(value[0], torch.Tensor): + cached[key] = [v.to(self.inference_state_device, non_blocking=True) for v in value] + else: + cached[key] = value + self._vision_features[frame_idx] = cached + + def get_vision_features(self, frame_idx: int) -> dict | None: + """Get cached vision features, automatically moved to inference device.""" + if frame_idx not in self._vision_features: + return None + + cached = self._vision_features[frame_idx] + moved = {} + for key, value in cached.items(): + if isinstance(value, torch.Tensor): + moved[key] = value.to(self.inference_device, non_blocking=True) + elif isinstance(value, (list, tuple)) and value and isinstance(value[0], torch.Tensor): + moved[key] = [v.to(self.inference_device, non_blocking=True) for v in value] + else: + moved[key] = value + return moved + + def clear_all(self): + """Clear all cached data.""" + self._vision_features.clear() + + +class Sam3TrackerVideoInferenceSession: + r""" + Manages video inference session parameters, state and cache. + + Args: + video (`torch.FloatTensor`, *optional*): + The video to process. No need to provide when streaming. + video_height (`int`, *optional*): + The height of the video. + video_width (`int`, *optional*): + The width of the video. + inference_device (`torch.device`, *optional*, defaults to `"cpu"`): + The device to use for inference. + inference_state_device (`torch.device`, *optional*, defaults to `"cpu"`): + The device to store the inference state on. + video_storage_device (`torch.device`, *optional*, defaults to `"cpu"`): + The device to store the video on. + dtype (`torch.dtype`, *optional*, defaults to `"float32"`): + The dtype to use for the video. + max_vision_features_cache_size (`int`, *optional*, defaults to 1): + The maximum number of vision features to cache. + """ + + def __init__( + self, + video: torch.FloatTensor | None = None, + video_height: int | None = None, + video_width: int | None = None, + inference_device: torch.device | str = "cpu", + inference_state_device: torch.device | str = "cpu", + video_storage_device: torch.device | str = "cpu", + dtype: torch.dtype | str = "float32", + max_vision_features_cache_size: int = 1, + ): + # store as a dictionary to avoid double memory allocation with torch.cat when adding new frames + self.processed_frames = ( + dict(enumerate(video.to(video_storage_device, dtype=dtype))) if video is not None else None + ) + self.video_height = video_height + self.video_width = video_width + + self.inference_device = inference_device + self.inference_state_device = inference_state_device + self.video_storage_device = video_storage_device + self.dtype = dtype + self.max_vision_features_cache_size = max_vision_features_cache_size + + # Cache for computed features + self.cache = Sam3TrackerVideoInferenceCache( + inference_device=self.inference_device, + inference_state_device=self.inference_state_device, + max_vision_features_cache_size=self.max_vision_features_cache_size, + ) + + # Persistent object tracking state + self._obj_id_to_idx = OrderedDict() + self._obj_idx_to_id = OrderedDict() + self.obj_ids = [] + + # Persistent user inputs + self.point_inputs_per_obj = {} + self.mask_inputs_per_obj = {} + + # Persistent model outputs/history + self.output_dict_per_obj = {} + self.frames_tracked_per_obj = {} + + # Session state flags + self.obj_with_new_inputs = [] + + @property + def num_frames(self) -> int | None: + return len(self.processed_frames) if self.processed_frames is not None else None + + # Object management + def obj_id_to_idx(self, obj_id: int) -> int: + """Map object ID to index, creating new entry if needed.""" + obj_idx = self._obj_id_to_idx.get(obj_id, None) + if obj_idx is not None: + return obj_idx + + obj_idx = len(self._obj_id_to_idx) + self._obj_id_to_idx[obj_id] = obj_idx + self._obj_idx_to_id[obj_idx] = obj_id + self.obj_ids = list(self._obj_id_to_idx) + + self.point_inputs_per_obj[obj_idx] = {} + self.mask_inputs_per_obj[obj_idx] = {} + self.output_dict_per_obj[obj_idx] = { + "cond_frame_outputs": {}, + "non_cond_frame_outputs": {}, + } + self.frames_tracked_per_obj[obj_idx] = {} + + return obj_idx + + # Video Inference specific functions + def obj_idx_to_id(self, obj_idx: int) -> int: + """Map model-side object index to client-side object id.""" + return self._obj_idx_to_id[obj_idx] + + def get_obj_num(self) -> int: + """Get the total number of unique object ids received so far in this session.""" + return len(self._obj_idx_to_id) + + # Input management with device handling + def add_point_inputs(self, obj_idx: int, frame_idx: int, inputs: dict): + """Add point inputs with automatic device placement.""" + device_inputs = {} + for key, value in inputs.items(): + if isinstance(value, torch.Tensor): + device_inputs[key] = value.to(self.inference_device, non_blocking=False) + else: + device_inputs[key] = value + self.point_inputs_per_obj[obj_idx][frame_idx] = device_inputs + + def remove_point_inputs(self, obj_idx: int, frame_idx: int): + """Remove point inputs.""" + self.point_inputs_per_obj[obj_idx].pop(frame_idx, None) + + def add_mask_inputs(self, obj_idx: int, frame_idx: int, inputs: torch.Tensor): + """Add mask inputs with automatic device placement.""" + self.mask_inputs_per_obj[obj_idx][frame_idx] = inputs.to( + self.inference_device, dtype=self.dtype, non_blocking=True + ) + + def remove_mask_inputs(self, obj_idx: int, frame_idx: int): + """Remove mask inputs.""" + self.mask_inputs_per_obj[obj_idx].pop(frame_idx, None) + + # Output management with smart device placement + def store_output( + self, + obj_idx: int, + frame_idx: int, + output_key: str | None = None, + output_value: torch.Tensor | dict | None = None, + is_conditioning_frame: bool = True, + ): + """ + Store output with smart device management. + If output_key is None, the output is stored as a dictionary. + + Args: + obj_idx (int): The index of the object. + frame_idx (int): The index of the frame. + output_key (Optional[str]): The key of the output. If None, the output is stored as a dictionary. + output_value (Optional[Union[torch.Tensor, dict]]): The value of the output. + is_conditioning_frame (bool): Whether the output is for a conditioning frame. + """ + storage_key = "cond_frame_outputs" if is_conditioning_frame else "non_cond_frame_outputs" + + if output_key is None and isinstance(output_value, dict): + self.output_dict_per_obj[obj_idx][storage_key][frame_idx] = {} + for key, value in output_value.items(): + self.store_output(obj_idx, frame_idx, key, value, is_conditioning_frame) + return + + # Device placement: small tensors stay on inference device, large ones go to inference state device + if output_key in ["object_pointer", "object_score_logits"]: # Small tensors + self.output_dict_per_obj[obj_idx][storage_key][frame_idx][output_key] = output_value + elif isinstance(output_value, torch.Tensor): # Large tensors like masks, features + self.output_dict_per_obj[obj_idx][storage_key][frame_idx][output_key] = output_value.to( + self.inference_state_device, non_blocking=True + ) + else: + self.output_dict_per_obj[obj_idx][storage_key][frame_idx][output_key] = output_value + + def get_output( + self, + obj_idx: int, + frame_idx: int, + output_key: str, + is_conditioning_frame: bool = True, + ): + """ + Get output with smart device management. + + Args: + obj_idx (int): The index of the object. + frame_idx (int): The index of the frame. + output_key (str): The key of the output. + is_conditioning_frame (bool): Whether the output is for a conditioning frame. + """ + storage_key = "cond_frame_outputs" if is_conditioning_frame else "non_cond_frame_outputs" + out = self.output_dict_per_obj[obj_idx][storage_key].get(frame_idx, None) + # move to inference device if needed + if out is None: + return None + value = out[output_key] + if isinstance(value, torch.Tensor): + value = value.to(self.inference_device, non_blocking=True) + return value + + # Video frame management + def add_new_frame(self, pixel_values: torch.Tensor, frame_idx: int | None = None) -> int: + """Add new frame with automatic device placement.""" + pixel_values = pixel_values.to(self.video_storage_device, dtype=self.dtype, non_blocking=True) + if pixel_values.dim() == 4: + pixel_values = pixel_values.squeeze(0) + + if frame_idx is None: + frame_idx = len(self.processed_frames) if self.processed_frames is not None else 0 + + if self.processed_frames is None: + self.processed_frames = {frame_idx: pixel_values} + else: + self.processed_frames[frame_idx] = pixel_values + + return frame_idx + + def get_frame(self, frame_idx: int) -> torch.Tensor: + """Get frame from video.""" + return self.processed_frames[frame_idx].to(self.inference_device, non_blocking=True) + + def reset_tracking_data(self): + """Reset tracking data but keep cache.""" + self._obj_id_to_idx.clear() + self._obj_idx_to_id.clear() + self.obj_ids.clear() + self.point_inputs_per_obj.clear() + self.mask_inputs_per_obj.clear() + self.output_dict_per_obj.clear() + self.frames_tracked_per_obj.clear() + self.obj_with_new_inputs = [] + # Note: cache and video data are preserved + + def reset_inference_session(self): + """Reset tracking data and cache.""" + self._obj_id_to_idx.clear() + self._obj_idx_to_id.clear() + self.obj_ids.clear() + self.point_inputs_per_obj.clear() + self.mask_inputs_per_obj.clear() + self.output_dict_per_obj.clear() + self.frames_tracked_per_obj.clear() + self.obj_with_new_inputs = [] + self.cache.clear_all() + + +class Sam3TrackerVideoLayerNorm(nn.LayerNorm): + r"""LayerNorm that supports two data formats: channels_last (default) or channels_first. + The ordering of the dimensions in the inputs. channels_last corresponds to inputs with shape (batch_size, height, + width, channels) while channels_first corresponds to inputs with shape (batch_size, channels, height, width). + """ + + def __init__(self, normalized_shape, *, eps=1e-6, data_format="channels_last", **kwargs): + super().__init__(normalized_shape, eps=eps, **kwargs) + if data_format not in ["channels_last", "channels_first"]: + raise NotImplementedError(f"Unsupported data format: {data_format}") + self.data_format = data_format + + def forward(self, features: torch.Tensor) -> torch.Tensor: + """ + Args: + features: Tensor of shape (batch_size, channels, height, width) OR (batch_size, height, width, channels) + """ + if self.data_format == "channels_first": + features = features.permute(0, 2, 3, 1) + features = super().forward(features) + features = features.permute(0, 3, 1, 2) + else: + features = super().forward(features) + return features + + +# copied and adapted from original implementation, also practically equal to DetrSinePositionEmbedding +class Sam3TrackerVideoPositionEmbeddingSine(nn.Module): + """ + This is a more standard version of the position embedding, very similar to the one used by the Attention is all you + need paper, generalized to work on images. + """ + + def __init__( + self, num_pos_feats: int = 64, temperature: int = 10000, normalize: bool = False, scale: float | None = None + ): + super().__init__() + if scale is not None and normalize is False: + raise ValueError("normalize should be True if scale is passed") + self.num_pos_feats = num_pos_feats + self.temperature = temperature + self.normalize = normalize + self.scale = 2 * math.pi if scale is None else scale + + @compile_compatible_method_lru_cache(maxsize=1) + def forward( + self, + shape: torch.Size, + device: torch.device | str, + dtype: torch.dtype, + mask: Tensor | None = None, + ) -> Tensor: + if mask is None: + mask = torch.zeros((shape[0], shape[2], shape[3]), device=device, dtype=torch.bool) + not_mask = (~mask).to(dtype) + y_embed = not_mask.cumsum(1) + x_embed = not_mask.cumsum(2) + if self.normalize: + eps = 1e-6 + y_embed = y_embed / (y_embed[:, -1:, :] + eps) * self.scale + x_embed = x_embed / (x_embed[:, :, -1:] + eps) * self.scale + + dim_t = torch.arange(self.num_pos_feats, dtype=torch.int64, device=device).to(dtype) + dim_t = self.temperature ** (2 * torch.div(dim_t, 2, rounding_mode="floor") / self.num_pos_feats) + + pos_x = x_embed[:, :, :, None] / dim_t + pos_y = y_embed[:, :, :, None] / dim_t + pos_x = torch.stack((pos_x[:, :, :, 0::2].sin(), pos_x[:, :, :, 1::2].cos()), dim=4).flatten(3) + pos_y = torch.stack((pos_y[:, :, :, 0::2].sin(), pos_y[:, :, :, 1::2].cos()), dim=4).flatten(3) + pos = torch.cat((pos_y, pos_x), dim=3).permute(0, 3, 1, 2) + return pos + + +def eager_attention_forward( + module: nn.Module, + query: torch.Tensor, + key: torch.Tensor, + value: torch.Tensor, + attention_mask: torch.Tensor | None, + scaling: float, + dropout: float = 0.0, + **kwargs, +): + attn_weights = torch.matmul(query, key.transpose(2, 3)) * scaling + if attention_mask is not None: + attn_weights = attn_weights + attention_mask + + attn_weights = nn.functional.softmax(attn_weights, dim=-1, dtype=torch.float32).to(query.dtype) + attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training) + attn_output = torch.matmul(attn_weights, value) + attn_output = attn_output.transpose(1, 2).contiguous() + + return attn_output, attn_weights + + +class Sam3TrackerVideoAttention(nn.Module): + """ + SAM3_TRACKER_VIDEO's attention layer that allows for downscaling the size of the embedding after projection to queries, keys, and + values. + """ + + def __init__(self, config, downsample_rate=None): + super().__init__() + downsample_rate = config.attention_downsample_rate if downsample_rate is None else downsample_rate + self.config = config + self.hidden_size = config.hidden_size + self.internal_dim = config.hidden_size // downsample_rate + self.num_attention_heads = config.num_attention_heads + self.head_dim = self.internal_dim // config.num_attention_heads + self.scaling = self.head_dim**-0.5 + self.is_causal = False + + self.q_proj = nn.Linear(self.hidden_size, self.internal_dim) + self.k_proj = nn.Linear(self.hidden_size, self.internal_dim) + self.v_proj = nn.Linear(self.hidden_size, self.internal_dim) + self.o_proj = nn.Linear(self.internal_dim, self.hidden_size) + + def forward( + self, + query: torch.Tensor, + key: torch.Tensor, + value: torch.Tensor, + attention_similarity: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor, torch.Tensor]: + # Input projections + batch_size, point_batch_size = query.shape[:2] + new_shape = (batch_size * point_batch_size, -1, self.num_attention_heads, self.head_dim) + + query = self.q_proj(query).view(*new_shape).transpose(1, 2) + key = self.k_proj(key).view(*new_shape).transpose(1, 2) + value = self.v_proj(value).view(*new_shape).transpose(1, 2) + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, eager_attention_forward + ) + + if is_flash_attention_requested(self.config) and attention_similarity is not None: + # Target guided masks are represented as float masks and are incompatible with Flash Attention + # Fallback to SDPA for this call only so the rest of the model can still benefit from FA + attention_interface = ALL_ATTENTION_FUNCTIONS["sdpa"] + logger.warning_once( + "Falling back to SDPA for target-guided attention because " + "Flash Attention does not support additive bias masks." + ) + + attn_output, attn_weights = attention_interface( + self, + query, + key, + value, + attention_mask=attention_similarity, + dropout=0.0, + scaling=self.scaling, + is_causal=self.is_causal, + **kwargs, + ) + + attn_output = attn_output.reshape( + batch_size, point_batch_size, -1, self.num_attention_heads * self.head_dim + ).contiguous() + attn_output = self.o_proj(attn_output) + + return attn_output, attn_weights + + +class Sam3TrackerVideoTwoWayAttentionBlock(GradientCheckpointingLayer): + def __init__(self, config: Sam3TrackerVideoMaskDecoderConfig, skip_first_layer_pe: bool = False): + """ + A transformer block with four layers: + (1) self-attention of sparse inputs (2) cross attention of sparse inputs -> dense inputs (3) mlp block on + sparse inputs (4) cross attention of dense inputs -> sparse inputs + + Arguments: + config (`Sam3TrackerVideoMaskDecoderConfig`): + The configuration file used to instantiate the block + attention_downsample_rate (*optionalk*, int, defaults to 2): + The downsample ratio of the block used to reduce the inner dim of the attention. + skip_first_layer_pe (*optional*, bool, defaults to `False`): + Whether or not to skip the addition of the query_point_embedding on the first layer. + """ + super().__init__() + self.self_attn = Sam3TrackerVideoAttention(config, downsample_rate=1) + self.layer_norm1 = nn.LayerNorm(config.hidden_size) + + self.cross_attn_token_to_image = Sam3TrackerVideoAttention(config) + self.layer_norm2 = nn.LayerNorm(config.hidden_size) + + self.mlp = Sam3TrackerVideoFeedForward( + config.hidden_size, config.mlp_dim, config.hidden_size, num_layers=config.num_hidden_layers + ) + self.layer_norm3 = nn.LayerNorm(config.hidden_size) + + self.layer_norm4 = nn.LayerNorm(config.hidden_size) + self.cross_attn_image_to_token = Sam3TrackerVideoAttention(config) + + self.skip_first_layer_pe = skip_first_layer_pe + + def forward( + self, + queries: Tensor, + keys: Tensor, + query_point_embedding: Tensor, + key_point_embedding: Tensor, + attention_similarity: Tensor, + **kwargs: Unpack[TransformersKwargs], + ): + # Self attention block + if self.skip_first_layer_pe: + queries, _ = self.self_attn(query=queries, key=queries, value=queries) + else: + query = queries + query_point_embedding + attn_out, _ = self.self_attn(query=query, key=query, value=queries) + queries = queries + attn_out + queries = self.layer_norm1(queries) + + # Cross attention block, tokens attending to image embedding + query = queries + query_point_embedding + key = keys + key_point_embedding + + attn_out, _ = self.cross_attn_token_to_image( + query=query, key=key, value=keys, attention_similarity=attention_similarity + ) + queries = queries + attn_out + + queries = self.layer_norm2(queries) + + # MLP block + mlp_out = self.mlp(queries) + queries = queries + mlp_out + queries = self.layer_norm3(queries) + + # Cross attention block, image embedding attending to tokens + query = queries + query_point_embedding + key = keys + key_point_embedding + + attn_out, _ = self.cross_attn_image_to_token(query=key, key=query, value=queries) + keys = keys + attn_out + + keys = self.layer_norm4(keys) + return queries, keys, attn_out + + +class Sam3TrackerVideoFeedForward(nn.Module): + def __init__( + self, + input_dim: int, + hidden_dim: int, + output_dim: int, + num_layers: int, + activation: str = "relu", + sigmoid_output: bool = False, + ): + super().__init__() + self.num_layers = num_layers + self.activation = ACT2FN[activation] + self.proj_in = nn.Linear(input_dim, hidden_dim) + self.proj_out = nn.Linear(hidden_dim, output_dim) + self.layers = nn.ModuleList([nn.Linear(hidden_dim, hidden_dim) for _ in range(num_layers - 2)]) + self.sigmoid_output = sigmoid_output + + def forward(self, hidden_states): + hidden_states = self.proj_in(hidden_states) + hidden_states = self.activation(hidden_states) + for layer in self.layers: + hidden_states = self.activation(layer(hidden_states)) + + hidden_states = self.proj_out(hidden_states) + if self.sigmoid_output: + hidden_states = F.sigmoid(hidden_states) + return hidden_states + + +@dataclass +@auto_docstring(custom_intro="Base class for the Sam3TrackerVideo model's output.") +class Sam3TrackerVideoImageSegmentationOutput(ModelOutput): + r""" + iou_scores (`torch.FloatTensor` of shape `(batch_size, point_batch_size, num_masks)`): + The Intersection over Union (IoU) scores of the predicted masks. + pred_masks (`torch.FloatTensor` of shape `(batch_size, point_batch_size, num_masks, height, width)`): + The predicted low-resolution masks. This is an alias for `low_res_masks`. These masks need to be post-processed + by the processor to be brought to the original image size. + object_score_logits (`torch.FloatTensor` of shape `(batch_size, point_batch_size, 1)`): + Logits for the object score, indicating if an object is present. + image_embeddings (`tuple(torch.FloatTensor)`): + The features from the FPN, which are used by the mask decoder. This is a tuple of `torch.FloatTensor` where each + tensor has shape `(batch_size, channels, height, width)`. + vision_hidden_states (`tuple(torch.FloatTensor)`, *optional*, returned when `output_hidden_states=True`): + Tuple of `torch.FloatTensor` (one for the output of each stage) of shape `(batch_size, height, width, hidden_size)`. + Hidden-states of the vision model at the output of each stage. + vision_attentions (`tuple(torch.FloatTensor)`, *optional*, returned when `output_attentions=True`): + Tuple of `torch.FloatTensor` (one for each layer) of shape `(batch_size, num_heads, sequence_length, sequence_length)`. + Attentions weights of the vision model. + mask_decoder_attentions (`tuple(torch.FloatTensor)`, *optional*, returned when `output_attentions=True`): + Tuple of `torch.FloatTensor` (one for each layer) of shape `(batch_size, num_heads, sequence_length, sequence_length)`. + Attentions weights of the mask decoder. + high_res_masks (`torch.FloatTensor` of shape `(batch_size, point_batch_size, num_masks, image_size, image_size)`, *optional*): + The predicted masks, upscaled to the original image size. Only used for Sam3TrackerVideoModel. + object_pointer (`torch.FloatTensor` of shape `(batch_size, point_batch_size, hidden_size)`, *optional*): + A tensor representing the object pointer, used for tracking in videos. Only used for Sam3TrackerVideoModel. + """ + + iou_scores: torch.FloatTensor | None = None + pred_masks: torch.FloatTensor | None = None + object_score_logits: torch.FloatTensor | None = None + image_embeddings: tuple[torch.FloatTensor, ...] = None + vision_hidden_states: tuple[torch.FloatTensor, ...] | None = None + vision_attentions: tuple[torch.FloatTensor, ...] | None = None + mask_decoder_attentions: tuple[torch.FloatTensor, ...] | None = None + + high_res_masks: torch.FloatTensor | None = None + object_pointer: torch.FloatTensor | None = None + + +@dataclass +@auto_docstring(custom_intro="Base class for the Sam2 model's output.") +class Sam3TrackerVideoSegmentationOutput(ModelOutput): + r""" + object_ids (`list[int]`, *optional*): + List of object IDs being tracked in the current frame. + pred_masks (`torch.FloatTensor` of shape `(batch_size, num_masks, height, width)`): + The predicted masks stored at the model's resolution. + object_score_logits (`torch.FloatTensor` of shape `(batch_size,)`, *optional*): + Logits for the object scores, indicating if objects are present. + frame_idx (`int`): + The frame index of the video. + """ + + object_ids: list[int] | None = None + pred_masks: torch.FloatTensor | None = None + object_score_logits: torch.FloatTensor | None = None + frame_idx: int | None = None + + +@auto_docstring +class Sam3TrackerVideoPreTrainedModel(PreTrainedModel): + config_class = Sam3TrackerVideoConfig + base_model_prefix = "sam3_tracker_video" + main_input_name = "pixel_values" + input_modalities = "video" + _supports_sdpa = True + _supports_flash_attn = True + _supports_attention_backend = True + + @torch.no_grad() + def _init_weights(self, module): + super()._init_weights(module) + if isinstance(module, Sam3TrackerVideoModel): + if module.no_memory_positional_encoding is not None: + init.zeros_(module.no_memory_positional_encoding) + if module.memory_temporal_positional_encoding is not None: + init.zeros_(module.memory_temporal_positional_encoding) + if module.no_object_pointer is not None: + init.zeros_(module.no_object_pointer) + if module.occlusion_spatial_embedding_parameter is not None: + init.zeros_(module.occlusion_spatial_embedding_parameter) + if isinstance(module, Sam3TrackerVideoMemoryFuserCXBlock): + if module.scale is not None: + init.zeros_(module.scale) + elif isinstance(module, Sam3TrackerVideoVisionRotaryEmbedding): + inv_freq = module.create_inv_freq() + init.copy_(module.rope_embeddings_cos, inv_freq.cos()) + init.copy_(module.rope_embeddings_sin, inv_freq.sin()) + elif isinstance(module, Sam3TrackerVideoPositionalEmbedding): + init.normal_(module.positional_embedding, std=module.scale) + + +class Sam3TrackerVideoVisionRotaryEmbedding(nn.Module): + """ + Vision Rotary Position Embedding for SAM2, following transformers library standards. + Supports 2D (axial) rotary embeddings for spatial dimensions. + """ + + def __init__(self, config: Sam3TrackerVideoConfig): + super().__init__() + self.dim = config.memory_attention_hidden_size // ( + config.memory_attention_downsample_rate * config.memory_attention_num_attention_heads + ) + # Ensure even dimension for proper axial splitting + if self.dim % 4 != 0: + raise ValueError("Dimension must be divisible by 4 for axial RoPE") + self.end_x, self.end_y = config.memory_attention_rope_feat_sizes + self.memory_attention_rope_theta = config.memory_attention_rope_theta + + # directly register the cos and sin embeddings as we have a fixed feature shape + inv_freq = self.create_inv_freq() + self.register_buffer("rope_embeddings_cos", inv_freq.cos(), persistent=False) + self.register_buffer("rope_embeddings_sin", inv_freq.sin(), persistent=False) + + @torch.no_grad() + def forward(self) -> tuple[torch.Tensor, torch.Tensor]: + # As the feature map size is fixed, we can just return the pre-computed embeddings. + return self.rope_embeddings_cos, self.rope_embeddings_sin + + def create_inv_freq(self): + freqs = 1.0 / ( + self.memory_attention_rope_theta ** (torch.arange(0, self.dim, 4)[: (self.dim // 4)].float() / self.dim) + ) + # Generate 2D position indices for axial rotary embedding + flattened_indices = torch.arange(self.end_x * self.end_y, dtype=torch.long) + x_positions = flattened_indices % self.end_x + y_positions = torch.div(flattened_indices, self.end_x, rounding_mode="floor") + freqs_x = torch.outer(x_positions, freqs).float() + freqs_y = torch.outer(y_positions, freqs).float() + inv_freq = torch.cat([freqs_x, freqs_y], dim=-1) + inv_freq = inv_freq.repeat_interleave(2, dim=-1) + return inv_freq + + +def rotate_pairwise(x): + """ + pairwise rotation of the hidden dims of the input. Differerent from Llama Half-Tensor Rotation. + + This is an optimized version of the following more explicit implementation: + ```python + x_rotated = torch.zeros_like(x, dtype=x.dtype, device=x.device) + x_rotated[..., ::2] = -x[..., 1::2] + x_rotated[..., 1::2] = x[..., ::2] + return x_rotated + ``` + """ + x = x.view(*x.shape[:-1], -1, 2) + x1, x2 = x.unbind(dim=-1) + x = torch.stack((-x2, x1), dim=-1) + return x.flatten(start_dim=-2) + + +# TODO: This leads to ~1e-07 max diff and ~1e-09 avg diff for q_embed and k_embed from the original implementation, most likely due to the use of complex tensors in the original implementation. +def apply_rotary_pos_emb_2d( + q: torch.Tensor, + k: torch.Tensor, + cos: torch.Tensor, + sin: torch.Tensor, + num_k_exclude_rope: int = 0, + repeat_freqs_k: bool = False, +) -> tuple[torch.Tensor, torch.Tensor]: + """ + Apply rotary position embedding to query and key tensors for vision models. + Follows the standard transformers library pattern. + + Args: + q: Query tensor of shape (..., seq_len, head_dim) + k: Key tensor of shape (..., seq_len, head_dim) + cos: Cosine position embedding of shape (seq_len, head_dim) + sin: Sine position embedding of shape (seq_len, head_dim) + repeat_freqs_k: Whether to repeat frequencies for keys (for cross-attention) + + Returns: + Rotated (q, k) tensors + """ + k_rot, k_pass = k[..., : k.shape[-2] - num_k_exclude_rope, :], k[..., k.shape[-2] - num_k_exclude_rope :, :] + q_embed = q.float() # force upscale to float32 as in the original implementation + q_embed = (q_embed * cos) + (rotate_pairwise(q_embed) * sin) + if k_rot.shape[-2] == 0: + # Handle case where keys might be empty due to dropout + return q_embed.type_as(q), torch.cat([k_rot, k_pass], dim=-2) + + # Handle key tensor - may need to repeat frequencies if different sequence length + if repeat_freqs_k and k_rot.shape[-2] != q.shape[-2]: + # Repeat cos/sin to match key sequence length + repeat_factor = k_rot.shape[-2] // q.shape[-2] + cos_k = cos.repeat(1, 1, repeat_factor, 1) + sin_k = sin.repeat(1, 1, repeat_factor, 1) + else: + cos_k = cos + sin_k = sin + + # Apply rotary embedding to keys + k_embed = k_rot.float() # force upscale to float32 as in the original implementation + k_embed = (k_embed * cos_k) + (rotate_pairwise(k_embed) * sin_k) + # Concatenate back to full shape + k_embed = torch.cat([k_embed.type_as(k), k_pass], dim=-2) + return q_embed.type_as(q), k_embed + + +class Sam3TrackerVideoRoPEAttention(nn.Module): + """Attention with rotary position encoding.""" + + def __init__( + self, + config: Sam3TrackerVideoConfig, + kv_in_dim: int | None = None, + rope_k_repeat=False, + ): + super().__init__() + self.config = config + self.hidden_size = config.memory_attention_hidden_size + self.internal_dim = self.hidden_size // config.memory_attention_downsample_rate + self.num_attention_heads = config.memory_attention_num_attention_heads + self.head_dim = self.internal_dim // config.memory_attention_num_attention_heads + self.scaling = self.head_dim**-0.5 + self.is_causal = False + + self.kv_in_dim = kv_in_dim if kv_in_dim is not None else self.hidden_size + + self.q_proj = nn.Linear(self.hidden_size, self.internal_dim) + self.k_proj = nn.Linear(self.kv_in_dim, self.internal_dim) + self.v_proj = nn.Linear(self.kv_in_dim, self.internal_dim) + self.o_proj = nn.Linear(self.internal_dim, self.hidden_size) + + self.rope_k_repeat = rope_k_repeat + self.dropout_p = config.memory_attention_rope_dropout + + def forward( + self, + query: torch.Tensor, + key: torch.Tensor, + value: torch.Tensor, + position_embeddings: tuple[torch.Tensor, torch.Tensor], + num_k_exclude_rope: int = 0, + **kwargs: Unpack[FlashAttentionKwargs], + ) -> Tensor: + # Input projections + batch_size, point_batch_size = query.shape[:2] + new_shape = (batch_size * point_batch_size, -1, self.num_attention_heads, self.head_dim) + + query = self.q_proj(query).view(*new_shape).transpose(1, 2) + key = self.k_proj(key).view(*new_shape).transpose(1, 2) + value = self.v_proj(value).view(*new_shape).transpose(1, 2) + + cos, sin = position_embeddings + # Apply rotary position encoding, excluding some keys if specified + query, key = apply_rotary_pos_emb_2d( + query, key, cos, sin, repeat_freqs_k=self.rope_k_repeat, num_k_exclude_rope=num_k_exclude_rope + ) + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, eager_attention_forward + ) + + attn_output, attn_weights = attention_interface( + self, + query, + key, + value, + attention_mask=None, + dropout=0.0 if not self.training else self.dropout_p, + scaling=self.scaling, + is_causal=self.is_causal, + **kwargs, + ) + attn_output = attn_output.reshape( + batch_size, point_batch_size, -1, self.num_attention_heads * self.head_dim + ).contiguous() + attn_output = self.o_proj(attn_output) + return attn_output, attn_weights + + +class Sam3TrackerVideoMemoryAttentionLayer(nn.Module): + def __init__(self, config: Sam3TrackerVideoConfig): + super().__init__() + hidden_size = config.memory_attention_hidden_size + self.self_attn = Sam3TrackerVideoRoPEAttention(config) + self.cross_attn_image = Sam3TrackerVideoRoPEAttention(config, kv_in_dim=64, rope_k_repeat=True) + + # Implementation of Feedforward model + self.linear1 = nn.Linear(hidden_size, config.memory_attention_feed_forward_hidden_size) + self.dropout = nn.Dropout(config.memory_attention_dropout) + self.linear2 = nn.Linear(config.memory_attention_feed_forward_hidden_size, hidden_size) + + self.layer_norm1 = nn.LayerNorm(hidden_size) + self.layer_norm2 = nn.LayerNorm(hidden_size) + self.layer_norm3 = nn.LayerNorm(hidden_size) + self.dropout1 = nn.Dropout(config.memory_attention_dropout) + self.dropout2 = nn.Dropout(config.memory_attention_dropout) + self.dropout3 = nn.Dropout(config.memory_attention_dropout) + + self.activation = ACT2FN[config.memory_attention_feed_forward_hidden_act] + + def forward( + self, + queries: Tensor, + keys: Tensor, + key_point_embedding: Tensor, + rope_position_embeddings: tuple[Tensor, Tensor], + num_k_exclude_rope: int = 0, + ) -> torch.Tensor: + # Self-Attention + query = self.layer_norm1(queries) + query, _ = self.self_attn(query=query, key=query, value=query, position_embeddings=rope_position_embeddings) + queries = queries + self.dropout1(query) + + # Cross-Attention + query = self.layer_norm2(queries) + query, _ = self.cross_attn_image( + query=query, + key=keys + key_point_embedding, + value=keys, + position_embeddings=rope_position_embeddings, + num_k_exclude_rope=num_k_exclude_rope, + ) + queries = queries + self.dropout2(query) + # MLP + query = self.layer_norm3(queries) + query = self.linear2(self.dropout(self.activation(self.linear1(query)))) + queries = queries + self.dropout3(query) + return queries + + +class Sam3TrackerVideoMemoryAttention(nn.Module): + def __init__(self, config: Sam3TrackerVideoConfig): + super().__init__() + self.layers = nn.ModuleList( + [Sam3TrackerVideoMemoryAttentionLayer(config) for _ in range(config.memory_attention_num_layers)] + ) + self.layer_norm = nn.LayerNorm(config.memory_attention_hidden_size) + self.rotary_emb = Sam3TrackerVideoVisionRotaryEmbedding(config=config) + + def forward( + self, + current_vision_features: torch.Tensor, + memory: torch.Tensor, + current_vision_position_embeddings: Tensor | None = None, + memory_posision_embeddings: Tensor | None = None, + num_object_pointer_tokens: int = 0, + ): + """ + Args: + current_vision_features (`torch.FloatTensor`): + The current vision features used for self-attention. + memory (`torch.FloatTensor`): + The memory features used for cross-attention. + current_vision_position_embeddings (`torch.FloatTensor`, *optional*): + The position embeddings for the current vision features. + memory_posision_embeddings (`torch.FloatTensor`, *optional*): + The position embeddings for the memory features. + num_object_pointer_tokens (`int`, *optional*, defaults to 0): + The number of object pointer tokens. + """ + output = current_vision_features + if current_vision_position_embeddings is not None: + output = output + 0.1 * current_vision_position_embeddings + + # Convert to batch first + output = output.transpose(0, 1) + memory = memory.transpose(0, 1).unsqueeze(1) + memory_posision_embeddings = memory_posision_embeddings.transpose(0, 1).unsqueeze(1) + rope_position_embeddings = self.rotary_emb() + for layer in self.layers: + output = layer( + queries=output.unsqueeze(1) if output.ndim == 3 else output, + keys=memory, + key_point_embedding=memory_posision_embeddings, + rope_position_embeddings=rope_position_embeddings, + num_k_exclude_rope=num_object_pointer_tokens, + ) + + normed_output = self.layer_norm(output) + + # Convert back to seq first + normed_output = normed_output.transpose(0, 1) + + return normed_output + + +# Lightly adapted from ConvNext (https://github.com/facebookresearch/ConvNeXt) +class Sam3TrackerVideoMemoryFuserCXBlock(GradientCheckpointingLayer): + def __init__(self, config: Sam3TrackerVideoConfig): + super().__init__() + self.depthwise_conv = nn.Conv2d( + config.memory_fuser_embed_dim, + config.memory_fuser_embed_dim, + kernel_size=config.memory_fuser_kernel_size, + padding=config.memory_fuser_padding, + groups=config.memory_fuser_embed_dim, + ) # depthwise conv + self.layer_norm = Sam3TrackerVideoLayerNorm( + config.memory_fuser_embed_dim, eps=1e-6, data_format="channels_first" + ) + self.activation = ACT2FN[config.memory_fuser_hidden_act] + self.pointwise_conv1 = nn.Linear( + config.memory_fuser_embed_dim, config.memory_fuser_intermediate_dim + ) # pointwise/1x1 convs, implemented with linear layers + self.pointwise_conv2 = nn.Linear(config.memory_fuser_intermediate_dim, config.memory_fuser_embed_dim) + self.scale = nn.Parameter( + config.memory_fuser_layer_scale_init_value * torch.ones(config.memory_fuser_embed_dim), + requires_grad=True, + ) + + def forward(self, hidden_states): + input = hidden_states + hidden_states = self.depthwise_conv(hidden_states) + hidden_states = self.layer_norm(hidden_states) + hidden_states = hidden_states.permute(0, 2, 3, 1) # (N, C, H, W) -> (N, H, W, C) + hidden_states = self.pointwise_conv1(hidden_states) + hidden_states = self.activation(hidden_states) + hidden_states = self.pointwise_conv2(hidden_states) + hidden_states = self.scale * hidden_states + hidden_states = hidden_states.permute(0, 3, 1, 2) # (N, H, W, C) -> (N, C, H, W) + + hidden_states = input + hidden_states + return hidden_states + + +class Sam3TrackerVideoMemoryFuser(nn.Module): + def __init__(self, config: Sam3TrackerVideoConfig): + super().__init__() + self.layers = nn.ModuleList( + [Sam3TrackerVideoMemoryFuserCXBlock(config) for _ in range(config.memory_fuser_num_layers)] + ) + + def forward(self, hidden_states): + # normally hidden_states: (N, C, H, W) + for layer in self.layers: + hidden_states = layer(hidden_states) + return hidden_states + + +class Sam3TrackerVideoMaskDownSamplerLayer(nn.Module): + def __init__(self, config: Sam3TrackerVideoConfig, in_channels: int, out_channels: int): + super().__init__() + self.conv = nn.Conv2d( + in_channels, + out_channels, + kernel_size=config.mask_downsampler_kernel_size, + stride=config.mask_downsampler_stride, + padding=config.mask_downsampler_padding, + ) + self.layer_norm = Sam3TrackerVideoLayerNorm(out_channels, eps=1e-6, data_format="channels_first") + self.activation = ACT2FN[config.mask_downsampler_hidden_act] + + def forward(self, x): + return self.activation(self.layer_norm(self.conv(x))) + + +class Sam3TrackerVideoMaskDownSampler(nn.Module): + """ + Progressively downsample a mask by total_stride, each time by stride. + Note that LayerNorm is applied per *token*, like in ViT. + + With each downsample (by a factor stride**2), channel capacity increases by the same factor. + In the end, we linearly project to embed_dim channels. + """ + + def __init__(self, config: Sam3TrackerVideoConfig): + super().__init__() + + num_layers = int(math.log2(config.mask_downsampler_total_stride) // math.log2(config.mask_downsampler_stride)) + + self.layers = nn.ModuleList() + self.activation = ACT2FN[config.mask_downsampler_hidden_act] + mask_in_chans, mask_out_chans = 1, 1 + for _ in range(num_layers): + mask_out_chans = mask_in_chans * (config.mask_downsampler_stride**2) + self.layers.append(Sam3TrackerVideoMaskDownSamplerLayer(config, mask_in_chans, mask_out_chans)) + mask_in_chans = mask_out_chans + + self.final_conv = nn.Conv2d(mask_out_chans, config.mask_downsampler_embed_dim, kernel_size=1) + + def forward(self, x): + for layer in self.layers: + x = layer(x) + x = self.final_conv(x) + return x + + +class Sam3TrackerVideoMemoryEncoder(nn.Module): + def __init__(self, config: Sam3TrackerVideoConfig): + super().__init__() + + hidden_size = config.memory_encoder_hidden_size + output_channels = config.memory_encoder_output_channels + self.mask_downsampler = Sam3TrackerVideoMaskDownSampler(config) + self.feature_projection = nn.Conv2d(hidden_size, hidden_size, kernel_size=1) + self.memory_fuser = Sam3TrackerVideoMemoryFuser(config) + self.position_encoding = Sam3TrackerVideoPositionEmbeddingSine( + num_pos_feats=output_channels // 2, normalize=True + ) + self.projection = nn.Conv2d(hidden_size, output_channels, kernel_size=1) + + def forward( + self, + vision_features: torch.Tensor, + masks: torch.Tensor, + ) -> tuple[torch.Tensor, torch.Tensor]: + ## Process masks + masks = self.mask_downsampler(masks) + ## Fuse pixel_features and downsampled masks + + vision_features = self.feature_projection(vision_features) + vision_features = vision_features + masks + vision_features = self.memory_fuser(vision_features) + vision_features = self.projection(vision_features) + + vision_pos_enc = self.position_encoding(vision_features.shape, vision_features.device, vision_features.dtype) + + return vision_features, vision_pos_enc + + +@dataclass +@auto_docstring(custom_intro="Base class for the vision encoder's outputs.") +class Sam3TrackerVideoVisionEncoderOutput(BaseModelOutputWithPooling): + r""" + last_hidden_state (`torch.FloatTensor` of shape `(batch_size, height, width, hidden_size)`): + Sequence of hidden-states at the output of the last layer of the model. + hidden_states (`tuple(torch.FloatTensor)`, *optional*, returned when `output_hidden_states=True` is passed or when `config.output_hidden_states=True`): + Tuple of `torch.FloatTensor` (one for the output of the embeddings, if the model has an embedding layer, + + one for the output of each stage) of shape `(batch_size, height, width, hidden_size)`. Hidden-states of the + model at the output of each stage. + attentions (`tuple(torch.FloatTensor)`, *optional*, returned when `output_attentions=True` is passed or when `config.output_attentions=True`): + Tuple of `torch.FloatTensor` (one for each layer) of shape `(batch_size, num_heads, sequence_length, + sequence_length)`. Attentions weights after the attention softmax, used to compute the weighted average in + the self-attention heads. + fpn_hidden_states (`tuple(torch.FloatTensor)`): + Tuple of `torch.FloatTensor` (one for each feature level, from high to low resolution) of shape + `(batch_size, hidden_size, height, width)`. Feature maps from the Feature Pyramid Network neck. + fpn_position_encoding (`tuple(torch.FloatTensor)`): + Tuple of `torch.FloatTensor` (one for each feature level, from high to low resolution) of shape + `(batch_size, hidden_size, height, width)`. Positional encodings corresponding to the `fpn_hidden_states`. + """ + + fpn_hidden_states: torch.FloatTensor | None = None + fpn_position_encoding: torch.FloatTensor | None = None + + +class Sam3TrackerVideoPositionalEmbedding(nn.Module): + def __init__(self, config: Sam3TrackerVideoPromptEncoderConfig): + super().__init__() + self.scale = config.scale + positional_embedding = self.scale * torch.randn((2, config.hidden_size // 2)) + self.register_buffer("positional_embedding", positional_embedding) + + def forward(self, input_coords, input_shape=None): + """Positionally encode points that are normalized to [0,1].""" + coordinates = input_coords.clone() + + if input_shape is not None: + coordinates[:, :, :, 0] = coordinates[:, :, :, 0] / input_shape[1] + coordinates[:, :, :, 1] = coordinates[:, :, :, 1] / input_shape[0] + coordinates.to(torch.float32) + + # assuming coords are in [0, 1]^2 square and have d_1 x ... x d_n x 2 shape + coordinates = 2 * coordinates - 1 + coordinates = coordinates.to(self.positional_embedding.dtype) + coordinates = coordinates @ self.positional_embedding + coordinates = 2 * np.pi * coordinates + # outputs d_1 x ... x d_n x channel shape + return torch.cat([torch.sin(coordinates), torch.cos(coordinates)], dim=-1) + + +class Sam3TrackerVideoMaskEmbedding(nn.Module): + def __init__(self, config: Sam3TrackerVideoPromptEncoderConfig): + super().__init__() + self.mask_input_channels = config.mask_input_channels // 4 + self.activation = ACT2FN[config.hidden_act] + self.conv1 = nn.Conv2d(1, self.mask_input_channels, kernel_size=2, stride=2) + self.conv2 = nn.Conv2d(self.mask_input_channels, config.mask_input_channels, kernel_size=2, stride=2) + self.conv3 = nn.Conv2d(config.mask_input_channels, config.hidden_size, kernel_size=1) + self.layer_norm1 = Sam3TrackerVideoLayerNorm( + self.mask_input_channels, eps=config.layer_norm_eps, data_format="channels_first" + ) + self.layer_norm2 = Sam3TrackerVideoLayerNorm( + self.mask_input_channels * 4, eps=config.layer_norm_eps, data_format="channels_first" + ) + + def forward(self, masks): + hidden_states = self.conv1(masks) + hidden_states = self.layer_norm1(hidden_states) + hidden_states = self.activation(hidden_states) + + hidden_states = self.conv2(hidden_states) + hidden_states = self.layer_norm2(hidden_states) + hidden_states = self.activation(hidden_states) + dense_embeddings = self.conv3(hidden_states) + return dense_embeddings + + +class Sam3TrackerVideoPromptEncoder(nn.Module): + def __init__(self, config: Sam3TrackerVideoPromptEncoderConfig): + super().__init__() + self.shared_embedding = Sam3TrackerVideoPositionalEmbedding(config) + self.mask_embed = Sam3TrackerVideoMaskEmbedding(config) + self.no_mask_embed = nn.Embedding(1, config.hidden_size) + + self.image_embedding_size = (config.image_size // config.patch_size, config.image_size // config.patch_size) + self.mask_input_size = (4 * config.image_size // config.patch_size, 4 * config.image_size // config.patch_size) + self.input_image_size = config.image_size + + self.point_embed = nn.Embedding(config.num_point_embeddings, config.hidden_size) + self.hidden_size = config.hidden_size + self.not_a_point_embed = nn.Embedding(1, config.hidden_size) + + def _embed_points(self, points: torch.Tensor, labels: torch.Tensor, pad: bool) -> torch.Tensor: + """Embeds point prompts.""" + points = points + 0.5 # Shift to center of pixel + if pad: + points = torch.nn.functional.pad(points, (0, 0, 0, 1), mode="constant", value=0) + labels = torch.nn.functional.pad(labels, (0, 1), mode="constant", value=-1) + input_shape = (self.input_image_size, self.input_image_size) + point_embedding = self.shared_embedding(points, input_shape) + + # torch.where and expanding the labels tensor is required by the ONNX export + point_embedding = torch.where(labels[..., None] == -1, self.not_a_point_embed.weight, point_embedding) + + # This is required for the ONNX export. The dtype, device need to be explicitly + # specified as otherwise torch.onnx.export interprets as double + point_embedding = torch.where( + labels[..., None] != -10, + point_embedding, + torch.zeros_like(point_embedding), + ) + + # Add point embeddings for labels >= 0 + point_embedding = point_embedding + self.point_embed(labels.clamp(min=0)) * (labels >= 0).unsqueeze(-1) + + return point_embedding + + def _embed_boxes(self, boxes: torch.Tensor) -> torch.Tensor: + """Embeds box prompts.""" + boxes = boxes + 0.5 # Shift to center of pixel + coords = boxes.view(*boxes.shape[:2], 2, 2) + # add padding point for consistency with the original implementation + coords = torch.nn.functional.pad(coords, (0, 0, 0, 1), mode="constant", value=0) + corner_embedding = self.shared_embedding(coords, (self.input_image_size, self.input_image_size)) + corner_embedding[:, :, 0, :] += self.point_embed.weight[2] + corner_embedding[:, :, 1, :] += self.point_embed.weight[3] + corner_embedding[:, :, 2, :] = self.not_a_point_embed.weight.expand_as(corner_embedding[:, :, 2, :]) + return corner_embedding + + def forward( + self, + input_points: tuple[torch.Tensor, torch.Tensor] | None, + input_labels: torch.Tensor | None, + input_boxes: torch.Tensor | None, + input_masks: torch.Tensor | None, + ) -> tuple[torch.Tensor, torch.Tensor]: + """ + Embeds different types of prompts, returning both sparse and dense embeddings. + + Args: + points (`torch.Tensor`, *optional*): + point coordinates and labels to embed. + boxes (`torch.Tensor`, *optional*): + boxes to embed + masks (`torch.Tensor`, *optional*): + masks to embed + """ + sparse_embeddings = None + batch_size = 1 + if input_points is not None: + batch_size = input_points.shape[0] + if input_labels is None: + raise ValueError("If points are provided, labels must also be provided.") + point_embeddings = self._embed_points(input_points, input_labels, pad=(input_boxes is None)) + sparse_embeddings = point_embeddings + if input_boxes is not None: + batch_size = input_boxes.shape[0] + box_embeddings = self._embed_boxes(input_boxes) + if sparse_embeddings is None: + sparse_embeddings = box_embeddings + else: + sparse_embeddings = torch.cat([sparse_embeddings, box_embeddings], dim=2) + if input_masks is not None: + dense_embeddings = self.mask_embed(input_masks) + else: + dense_embeddings = self.no_mask_embed.weight.reshape(1, -1, 1, 1).expand( + batch_size, -1, self.image_embedding_size[0], self.image_embedding_size[1] + ) + + return sparse_embeddings, dense_embeddings + + +class Sam3TrackerVideoTwoWayTransformer(nn.Module): + def __init__(self, config: Sam3TrackerVideoMaskDecoderConfig): + super().__init__() + self.config = config + + self.num_hidden_layers = config.num_hidden_layers + self.layers = nn.ModuleList() + + for i in range(self.num_hidden_layers): + self.layers.append(Sam3TrackerVideoTwoWayAttentionBlock(config, skip_first_layer_pe=(i == 0))) + + self.final_attn_token_to_image = Sam3TrackerVideoAttention(config) + self.layer_norm_final_attn = nn.LayerNorm(config.hidden_size) + + def forward( + self, + point_embeddings: Tensor, + image_embeddings: Tensor, + image_positional_embeddings: Tensor, + attention_similarity: Tensor, + target_embedding=None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple | BaseModelOutput: + if image_embeddings is None: + raise ValueError("You have to specify an image_embedding") + + image_embeddings = image_embeddings.flatten(2).permute(0, 2, 1).unsqueeze(1) + image_positional_embeddings = image_positional_embeddings.flatten(2).permute(0, 2, 1).unsqueeze(1) + + # Prepare queries + queries = point_embeddings + keys = image_embeddings + + # Apply transformer blocks and final layernorm + for layer in self.layers: + if target_embedding is not None: + queries += target_embedding + + queries, keys, _ = layer( + queries=queries, + keys=keys, + query_point_embedding=point_embeddings, + key_point_embedding=image_positional_embeddings, + attention_similarity=attention_similarity, + **kwargs, + ) + # Apply the final attention layer from the points to the image + query = queries + point_embeddings + key = keys + image_positional_embeddings + + attn_out, _ = self.final_attn_token_to_image(query=query, key=key, value=keys) + + queries = queries + attn_out + queries = self.layer_norm_final_attn(queries) + return queries, keys + + +class Sam3TrackerVideoMaskDecoder(nn.Module): + def __init__(self, config: Sam3TrackerVideoMaskDecoderConfig): + super().__init__() + self.config = config + self.hidden_size = config.hidden_size + + self.num_multimask_outputs = config.num_multimask_outputs + self.num_mask_tokens = config.num_multimask_outputs + 1 + + self.iou_token = nn.Embedding(1, self.hidden_size) + self.mask_tokens = nn.Embedding(self.num_mask_tokens, self.hidden_size) + + self.transformer = Sam3TrackerVideoTwoWayTransformer(config) + + # should we create a new class for this? + self.upscale_conv1 = nn.ConvTranspose2d(self.hidden_size, self.hidden_size // 4, kernel_size=2, stride=2) + self.upscale_conv2 = nn.ConvTranspose2d(self.hidden_size // 4, self.hidden_size // 8, kernel_size=2, stride=2) + self.upscale_layer_norm = Sam3TrackerVideoLayerNorm(self.hidden_size // 4, data_format="channels_first") + self.activation = nn.GELU() + + mlps_list = [] + for _ in range(self.num_mask_tokens): + mlps_list += [Sam3TrackerVideoFeedForward(self.hidden_size, self.hidden_size, self.hidden_size // 8, 3)] + self.output_hypernetworks_mlps = nn.ModuleList(mlps_list) + self.iou_prediction_head = Sam3TrackerVideoFeedForward( + self.hidden_size, + config.iou_head_hidden_dim, + self.num_mask_tokens, + config.iou_head_depth, + sigmoid_output=True, + ) + + self.conv_s0 = nn.Conv2d(config.hidden_size, config.hidden_size // 8, kernel_size=1, stride=1) + self.conv_s1 = nn.Conv2d(config.hidden_size, config.hidden_size // 4, kernel_size=1, stride=1) + + self.obj_score_token = nn.Embedding(1, self.hidden_size) + self.pred_obj_score_head = Sam3TrackerVideoFeedForward(self.hidden_size, self.hidden_size, 1, 3) + + self.dynamic_multimask_via_stability = config.dynamic_multimask_via_stability + self.dynamic_multimask_stability_delta = config.dynamic_multimask_stability_delta + self.dynamic_multimask_stability_thresh = config.dynamic_multimask_stability_thresh + + def forward( + self, + image_embeddings: torch.Tensor, + image_positional_embeddings: torch.Tensor, + sparse_prompt_embeddings: torch.Tensor, + dense_prompt_embeddings: torch.Tensor, + multimask_output: bool, + high_resolution_features: list[torch.Tensor], + attention_similarity: torch.Tensor | None = None, + target_embedding: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor, torch.Tensor, torch.Tensor, torch.Tensor]: + """ + Predict masks given image and prompt embeddings. + + Args: + image_embeddings (`torch.Tensor`): + The embeddings from the image encoder. + image_positional_embeddings (`torch.Tensor`): + Positional encoding with the shape of image_embeddings. + sparse_prompt_embeddings (`torch.Tensor`): + The embeddings of the points and boxes. + dense_prompt_embeddings (`torch.Tensor`): + The embeddings of the mask inputs. + multimask_output (`bool`): + Whether to return multiple masks or a single mask. + high_resolution_features (`list[torch.Tensor]`, *optional*): + The high-resolution features from the vision encoder. + attention_similarity (`torch.Tensor`, *optional*): + The attention similarity tensor. + target_embedding (`torch.Tensor`, *optional*): + The target embedding. + """ + batch_size, num_channels, height, width = image_embeddings.shape + point_batch_size = sparse_prompt_embeddings.shape[1] + # Concatenate output tokens + output_tokens = torch.cat( + [ + self.obj_score_token.weight, + self.iou_token.weight, + self.mask_tokens.weight, + ], + dim=0, + ) + output_tokens = output_tokens.repeat(batch_size, point_batch_size, 1, 1) + + if sparse_prompt_embeddings.shape[0] != 0: + tokens = torch.cat((output_tokens, sparse_prompt_embeddings), dim=2) + else: + tokens = output_tokens + point_embeddings = tokens.to(self.iou_token.weight.dtype) + + # Expand per-image data in batch direction to be per-mask + image_embeddings = image_embeddings + dense_prompt_embeddings + image_embeddings = image_embeddings.repeat_interleave(point_batch_size, dim=0) + image_positional_embeddings = image_positional_embeddings.repeat_interleave(point_batch_size, 0) + # Run the transformer + point_embeddings, image_embeddings = self.transformer( + point_embeddings=point_embeddings, + image_embeddings=image_embeddings, + image_positional_embeddings=image_positional_embeddings, + attention_similarity=attention_similarity, + target_embedding=target_embedding, + **kwargs, + ) + iou_token_out = point_embeddings[:, :, 1, :] + mask_tokens_out = point_embeddings[:, :, 2 : (2 + self.num_mask_tokens), :] + + # Upscale mask embeddings and predict masks using the mask tokens + image_embeddings = image_embeddings.transpose(2, 3).view( + batch_size * point_batch_size, num_channels, height, width + ) + + feat_s0, feat_s1 = high_resolution_features + feat_s0 = feat_s0.repeat_interleave(point_batch_size, dim=0) + feat_s1 = feat_s1.repeat_interleave(point_batch_size, dim=0) + upscaled_embedding = self.upscale_conv1(image_embeddings) + feat_s1 + upscaled_embedding = self.activation(self.upscale_layer_norm(upscaled_embedding)) + upscaled_embedding = self.activation(self.upscale_conv2(upscaled_embedding) + feat_s0) + + hyper_in_list: list[torch.Tensor] = [] + for i in range(self.num_mask_tokens): + current_mlp = self.output_hypernetworks_mlps[i] + hyper_in_list += [current_mlp(mask_tokens_out[:, :, i, :])] + hyper_in = torch.stack(hyper_in_list, dim=2) + + _, num_channels, height, width = upscaled_embedding.shape + upscaled_embedding = upscaled_embedding.view(batch_size, point_batch_size, num_channels, height * width) + masks = (hyper_in @ upscaled_embedding).view(batch_size, point_batch_size, -1, height, width) + + # Generate mask quality predictions + iou_pred = self.iou_prediction_head(iou_token_out) + object_score_logits = self.pred_obj_score_head(point_embeddings[:, :, 0, :]) + + # Select the correct mask or masks for output + if multimask_output: + mask_slice = slice(1, None) + masks = masks[:, :, mask_slice, :, :] + iou_pred = iou_pred[:, :, mask_slice] + elif self.dynamic_multimask_via_stability and not self.training: + mask_slice = slice(0, 1) + masks, iou_pred = self._dynamic_multimask_via_stability(masks, iou_pred) + else: + mask_slice = slice(0, 1) + masks = masks[:, :, mask_slice, :, :] + iou_pred = iou_pred[:, :, mask_slice] + + sam_tokens_out = mask_tokens_out[:, :, mask_slice] # [b, 3, c] shape + + return masks, iou_pred, sam_tokens_out, object_score_logits + + def _get_stability_scores(self, mask_logits): + """ + Compute stability scores of the mask logits based on the IoU between upper and + lower thresholds. + """ + mask_logits = mask_logits.flatten(-2) + stability_delta = self.dynamic_multimask_stability_delta + area_i = torch.sum(mask_logits > stability_delta, dim=-1).float() + area_u = torch.sum(mask_logits > -stability_delta, dim=-1).float() + stability_scores = torch.where(area_u > 0, area_i / area_u, 1.0) + return stability_scores + + def _dynamic_multimask_via_stability(self, all_mask_logits, all_iou_scores): + """ + When outputting a single mask, if the stability score from the current single-mask + output (based on output token 0) falls below a threshold, we instead select from + multi-mask outputs (based on output token 1~3) the mask with the highest predicted + IoU score. This is intended to ensure a valid mask for both clicking and tracking. + """ + # The best mask from multimask output tokens (1~3) + multimask_logits = all_mask_logits[:, :, 1:, :, :] + multimask_iou_scores = all_iou_scores[:, :, 1:] + best_scores_inds = torch.argmax(multimask_iou_scores, dim=-1) # [B, P] + best_scores_inds_expanded = best_scores_inds.unsqueeze(-1).unsqueeze(-1).unsqueeze(-1) + best_scores_inds_expanded = best_scores_inds_expanded.expand( + -1, -1, 1, multimask_logits.size(-2), multimask_logits.size(-1) + ) + best_multimask_logits = torch.gather(multimask_logits, 2, best_scores_inds_expanded) # [B, P, 1, H, W] + best_multimask_iou_scores = torch.gather(multimask_iou_scores, 2, best_scores_inds.unsqueeze(-1)) # [B, P, 1] + + # The mask from singlemask output token 0 and its stability score + singlemask_logits = all_mask_logits[:, :, 0:1, :, :] + singlemask_iou_scores = all_iou_scores[:, :, 0:1] + stability_scores = self._get_stability_scores(singlemask_logits) + is_stable = stability_scores >= self.dynamic_multimask_stability_thresh + + # Dynamically fall back to best multimask output upon low stability scores. + mask_logits_out = torch.where( + is_stable[..., None, None].expand_as(singlemask_logits), + singlemask_logits, + best_multimask_logits, + ) + iou_scores_out = torch.where( + is_stable.expand_as(singlemask_iou_scores), + singlemask_iou_scores, + best_multimask_iou_scores, + ) + return mask_logits_out, iou_scores_out + + +# a large negative value as a placeholder score for missing objects +NO_OBJ_SCORE = -1024.0 + + +def get_1d_sine_pe(pos_inds, dim, temperature=10000): + """ + Get 1D sine positional embedding as in the original Transformer paper. + """ + pe_dim = dim // 2 + dim_t = torch.arange(pe_dim, dtype=torch.float32, device=pos_inds.device) + dim_t = temperature ** (2 * (dim_t // 2) / pe_dim) + + pos_embed = pos_inds.unsqueeze(-1) / dim_t + pos_embed = torch.cat([pos_embed.sin(), pos_embed.cos()], dim=-1) + return pos_embed + + +@auto_docstring +class Sam3TrackerVideoModel(Sam3TrackerVideoPreTrainedModel): + input_modalities = ("video", "text") + _can_record_outputs = {"mask_decoder_attentions": OutputRecorder(Sam3TrackerVideoTwoWayAttentionBlock, index=2)} + _tied_weights_keys = {} + _keys_to_ignore_on_load_unexpected = [r"^detector_model."] + _checkpoint_conversion_mapping = { + r"tracker_model.(.+)": r"\1", # the regex allows to remove the prefix, and add it back in revert mode + "detector_model.vision_encoder.backbone.": "vision_encoder.backbone.", + "tracker_neck.": "vision_encoder.neck.", + } + + def __init__(self, config: Sam3TrackerVideoConfig, remove_vision_encoder: bool = False): + r""" + remove_vision_encoder (`bool`, *optional*, defaults to `False`): + Whether to remove the vision encoder. If True, the vision encoder will be set to None. + """ + # loading from a sam3_video config + if hasattr(config, "tracker_config") and config.tracker_config is not None: + tracker_config = config.tracker_config + if isinstance(tracker_config, dict): + tracker_config = Sam3TrackerVideoConfig(**tracker_config) + config = tracker_config + super().__init__(config) + self.shared_image_embedding = Sam3TrackerVideoPositionalEmbedding(config.prompt_encoder_config) + self.vision_encoder = AutoModel.from_config(config.vision_config) if not remove_vision_encoder else None + self.prompt_encoder = Sam3TrackerVideoPromptEncoder(config.prompt_encoder_config) + # The module using it is not a PreTrainedModel subclass so we need this + config.mask_decoder_config._attn_implementation = config._attn_implementation + self.mask_decoder = Sam3TrackerVideoMaskDecoder(config.mask_decoder_config) + + self.backbone_feature_sizes = config.vision_config.backbone_feature_sizes + # a single token to indicate no memory embedding from previous frames + self.hidden_dim = config.vision_config.fpn_hidden_size + self.no_memory_embedding = torch.nn.Parameter(torch.zeros(1, 1, self.hidden_dim)) + self.config = config + # For video sequence inference + self.image_size = config.image_size + self.memory_attention = Sam3TrackerVideoMemoryAttention(config) + self.memory_encoder = Sam3TrackerVideoMemoryEncoder(config) + self.no_memory_positional_encoding = torch.nn.Parameter( + torch.zeros(1, 1, config.vision_config.fpn_hidden_size) + ) + self.mem_dim = config.memory_encoder_output_channels + self.num_maskmem = config.num_maskmem # Number of memories accessible + # Temporal encoding of the memories + self.memory_temporal_positional_encoding = torch.nn.Parameter( + torch.zeros(self.num_maskmem, 1, 1, self.mem_dim) + ) + + self.no_object_pointer = torch.nn.Parameter(torch.zeros(1, self.hidden_dim)) + # A conv layer to downsample the mask prompt to stride 4 (the same stride as + # low-res SAM mask logits) and to change its scales from 0~1 to SAM logit scale, + # so that it can be fed into the SAM mask decoder to generate a pointer. + self.mask_downsample = torch.nn.Conv2d(1, 1, kernel_size=4, stride=4) + # a feedforward layer on SAM output tokens to turn them into object pointers + self.object_pointer_proj = Sam3TrackerVideoFeedForward(self.hidden_dim, self.hidden_dim, self.hidden_dim, 3) + + if self.config.enable_temporal_pos_encoding_for_object_pointers: + # a linear projection on temporal positional encoding in object pointers to + # avoid potential interference with spatial positional encoding + self.temporal_positional_encoding_projection_layer = torch.nn.Linear(self.hidden_dim, self.mem_dim) + else: + self.temporal_positional_encoding_projection_layer = torch.nn.Identity() + + self.occlusion_spatial_embedding_parameter = None # compatibility with Sam2 + if config.enable_occlusion_spatial_embedding: + self.occlusion_spatial_embedding_parameter = torch.nn.Parameter(torch.zeros(1, self.mem_dim)) + + self.post_init() + + def get_input_embeddings(self): + return self.vision_encoder.get_input_embeddings() + + def get_image_wide_positional_embeddings(self) -> torch.Tensor: + size = self.prompt_encoder.image_embedding_size + target_device = self.shared_image_embedding.positional_embedding.device + target_dtype = self.shared_image_embedding.positional_embedding.dtype + grid = torch.ones(size, device=target_device, dtype=target_dtype) + y_embed = grid.cumsum(dim=0) - 0.5 + x_embed = grid.cumsum(dim=1) - 0.5 + y_embed = y_embed / size[0] + x_embed = x_embed / size[1] + + positional_embedding = self.shared_image_embedding(torch.stack([x_embed, y_embed], dim=-1)) + return positional_embedding.permute(2, 0, 1).unsqueeze(0) # channel x height x width + + @torch.no_grad() + def get_image_embeddings( + self, + pixel_values: torch.FloatTensor, + **kwargs: Unpack[TransformersKwargs], + ) -> list[torch.Tensor]: + r""" + Returns the image embeddings by passing the pixel values through the vision encoder. + + Args: + pixel_values (`torch.FloatTensor` of shape `(batch_size, num_channels, height, width)`): + Input pixel values + """ + batch_size = pixel_values.shape[0] + image_outputs = self.get_image_features(pixel_values, return_dict=True, **kwargs) + feature_maps = image_outputs.fpn_hidden_states + + # add no memory embedding to the last feature map + feature_maps[-1] = feature_maps[-1] + self.no_memory_embedding + + # reshape feature maps to the same shape as the backbone feature sizes + image_embeddings = [ + feat.permute(1, 2, 0).view(batch_size, -1, *feat_size) + for feat, feat_size in zip(feature_maps, self.backbone_feature_sizes) + ] + + return image_embeddings + + @torch.no_grad() + def get_prompt_embeddings( + self, + input_points: torch.FloatTensor | None = None, + input_labels: torch.LongTensor | None = None, + input_boxes: torch.FloatTensor | None = None, + input_masks: torch.LongTensor | None = None, + ) -> tuple[torch.Tensor, torch.Tensor]: + r""" + Returns the prompt embeddings by passing the input points, labels, boxes and masks through the prompt encoder. + + Args: + input_points (`torch.FloatTensor` of shape `(batch_size, point_batch_size, num_points_per_image, 2)`): + Optional input points for the prompt encoder. The padding of the point is automatically done by the + processor. `point_batch_size` refers to the number of masks that we want the model to predict per + point. The model will output `point_batch_size` times 3 masks in total. + input_labels (`torch.LongTensor` of shape `(batch_size, point_batch_size, num_points_per_image)`): + Optional input labels for the prompt encoder. The padding of the labels is automatically done by the + processor, or can be fed by the user. + input_boxes (`torch.FloatTensor` of shape `(batch_size, num_boxes_per_image, 4)`): + Optional input boxes for the prompt encoder. The padding of the boxes is automatically done by the + processor. users can also pass manually the input boxes. + input_masks (`torch.LongTensor` of shape `(batch_size, image_size, image_size)`): + Optional input masks for the prompt encoder. + """ + prompt_output = self.prompt_encoder( + input_points=input_points, + input_labels=input_labels, + input_boxes=input_boxes, + input_masks=input_masks, + ) + return prompt_output + + @torch.inference_mode() + @auto_docstring(custom_intro="Propagate the objects through a streamed video frame.") + def forward( + self, + inference_session: Sam3TrackerVideoInferenceSession, + frame_idx: int | None = None, + frame: torch.Tensor | None = None, + reverse: bool = False, + run_mem_encoder: bool = True, + **kwargs, + ) -> Sam3TrackerVideoSegmentationOutput: + r""" + inference_session (`Sam3TrackerVideoInferenceSession`): + The video inference session object. + frame_idx (`int`, *optional*): + The index of the frame on which to run inference. No need to provide when inferring + on a new streamed frame. + frame (`torch.Tensor`, *optional*): + The frame to process. Provide when streaming. + reverse (`bool`, *optional*, defaults to `False`): + Whether to propagate in reverse. + run_mem_encoder (`bool`, *optional*, defaults to `True`): + Whether to run the memory encoder on predicted masks. The memory encoder is batched across all objects for efficiency. + """ + if frame is not None: + frame_idx = inference_session.add_new_frame(frame, frame_idx) + + if frame is not None and inference_session.get_obj_num() == 0: + raise ValueError("No objects are provided for tracking; please add inputs first.") + + num_objects = inference_session.get_obj_num() + pred_masks_per_obj = [None] * num_objects + object_score_logits_per_obj = [None] * num_objects + + # Collect data for batched memory encoding + objects_needing_memory_encoding = [] + high_res_masks_for_memory = [] + object_score_logits_for_memory = [] + is_mask_from_pts_per_obj = [] + + # Note: We avoid batched inference here because per-object inputs (clicks/masks) + # can differ across objects. + for obj_idx in range(num_objects): + obj_id = inference_session.obj_idx_to_id(obj_idx) + has_new_inputs = obj_id in inference_session.obj_with_new_inputs + has_cond_output = frame_idx in inference_session.output_dict_per_obj[obj_idx]["cond_frame_outputs"] + # If this object has no new inputs and this frame already has a + # conditioning output, reuse the cached masks instead of recomputing. + if (not has_new_inputs) and has_cond_output: + pred_masks = inference_session.get_output(obj_idx, frame_idx, "pred_masks", is_conditioning_frame=True) + object_score_logits = inference_session.get_output( + obj_idx, frame_idx, "object_score_logits", is_conditioning_frame=True + ) + is_init_cond_frame = True + else: + # Defaults when there are no new inputs + is_init_cond_frame = False + point_inputs = None + mask_inputs = None + + if has_new_inputs: + is_init_cond_frame = frame_idx not in inference_session.frames_tracked_per_obj[obj_idx] + if is_init_cond_frame: + reverse = False + point_inputs = inference_session.point_inputs_per_obj[obj_idx].get(frame_idx, None) + mask_inputs = inference_session.mask_inputs_per_obj[obj_idx].get(frame_idx, None) + if point_inputs is not None or mask_inputs is not None: + inference_session.obj_with_new_inputs.remove(obj_id) + + current_out = self._run_single_frame_inference( + inference_session=inference_session, + obj_idx=obj_idx, + frame_idx=frame_idx, + batch_size=1, # run on the slice of a single object + is_init_cond_frame=is_init_cond_frame, + point_inputs=point_inputs, + mask_inputs=mask_inputs, + reverse=reverse, + streaming=frame is not None, + ) + inference_session.store_output( + obj_idx, frame_idx, output_value=current_out, is_conditioning_frame=is_init_cond_frame + ) + pred_masks = current_out["pred_masks"] + object_score_logits = current_out["object_score_logits"] + + # Collect data for batched memory encoding + if run_mem_encoder and self.num_maskmem > 0: + objects_needing_memory_encoding.append(obj_idx) + high_res_masks_for_memory.append(current_out["high_res_masks"]) + object_score_logits_for_memory.append(object_score_logits) + is_mask_from_pts_per_obj.append(point_inputs is not None or mask_inputs is not None) + + pred_masks_per_obj[obj_idx] = pred_masks + object_score_logits_per_obj[obj_idx] = object_score_logits.squeeze(-1) + if not is_init_cond_frame: + # only for tracked frames, not for initial conditioning frames + inference_session.frames_tracked_per_obj[obj_idx][frame_idx] = {"reverse": reverse} + + # Batch encode memories for all objects at once + self._batch_encode_memories( + inference_session=inference_session, + frame_idx=frame_idx, + objects_needing_memory_encoding=objects_needing_memory_encoding, + high_res_masks_for_memory=high_res_masks_for_memory, + object_score_logits_for_memory=object_score_logits_for_memory, + is_mask_from_pts_per_obj=is_mask_from_pts_per_obj, + ) + + # Resize the output mask to the original video resolution (we directly use + # the mask scores on GPU for output to avoid any CPU conversion in between) + if len(pred_masks_per_obj) > 1: + all_pred_masks = torch.cat(pred_masks_per_obj, dim=0) + all_object_score_logits = torch.cat(object_score_logits_per_obj, dim=0) + else: + all_pred_masks = pred_masks_per_obj[0] + all_object_score_logits = object_score_logits_per_obj[0] + + return Sam3TrackerVideoSegmentationOutput( + object_ids=inference_session.obj_ids.copy(), + pred_masks=all_pred_masks, + object_score_logits=all_object_score_logits, + frame_idx=frame_idx, + ) + + @can_return_tuple + @auto_docstring + def get_image_features( + self, + pixel_values: torch.FloatTensor, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple | Sam3TrackerVideoVisionEncoderOutput: + r""" + pixel_values (`torch.FloatTensor`): + Input pixel values of shape `(batch_size, num_channels, height, width)`. + """ + vision_outputs: Sam3TrackerVideoVisionEncoderOutput = self.vision_encoder( + pixel_values, return_dict=True, **kwargs + ) + + feature_maps = vision_outputs.fpn_hidden_states + feature_maps_position_embeddings = vision_outputs.fpn_position_encoding + + # precompute projected level 0 and level 1 features in SAM decoder + # to avoid running it again on every SAM click + feature_maps = list(feature_maps[:-1]) + feature_maps[0] = self.mask_decoder.conv_s0(feature_maps[0]) + feature_maps[1] = self.mask_decoder.conv_s1(feature_maps[1]) + + # flatten NxCxHxW to HWxNxC + feature_maps = [feature_map.flatten(2).permute(2, 0, 1) for feature_map in feature_maps] + feature_maps_position_embeddings = [ + feature_map_position_embedding.flatten(2).permute(2, 0, 1) + for feature_map_position_embedding in feature_maps_position_embeddings[:-1] + ] + vision_outputs.fpn_hidden_states = feature_maps + vision_outputs.fpn_position_encoding = feature_maps_position_embeddings + + return vision_outputs + + def _prepare_vision_features( + self, + inference_session: Sam3TrackerVideoInferenceSession, + frame_idx: int, + batch_size: int, + ) -> tuple[torch.Tensor, list[torch.Tensor]]: + """Prepare vision features for a frame.""" + + # Check if features are cached + if cached_features := inference_session.cache.get_vision_features(frame_idx): + vision_feats = cached_features["vision_feats"] + vision_pos_embeds = cached_features["vision_pos_embeds"] + else: + # Compute features using image encoder + image_batch = inference_session.get_frame(frame_idx).unsqueeze(0) # Add batch dimension + image_outputs = self.get_image_features(image_batch, return_dict=True) + vision_feats = image_outputs.fpn_hidden_states + vision_pos_embeds = image_outputs.fpn_position_encoding + # Cache features + inference_session.cache.cache_vision_features( + frame_idx, {"vision_feats": vision_feats, "vision_pos_embeds": vision_pos_embeds} + ) + + # Expand to batch size if needed + if batch_size > 1: + vision_feats = vision_feats.expand(batch_size, -1, -1, -1) + vision_pos_embeds = [pe.expand(batch_size, -1, -1, -1) for pe in vision_pos_embeds] + + return vision_feats, vision_pos_embeds + + def _single_frame_forward( + self, + pixel_values: torch.FloatTensor | None = None, + input_points: torch.FloatTensor | None = None, + input_labels: torch.LongTensor | None = None, + input_boxes: torch.FloatTensor | None = None, + input_masks: torch.LongTensor | None = None, + image_embeddings: torch.FloatTensor | None = None, + multimask_output: bool = True, + attention_similarity: torch.FloatTensor | None = None, + target_embedding: torch.FloatTensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> Sam3TrackerVideoImageSegmentationOutput: + """ + input_points (`torch.FloatTensor` of shape `(batch_size, num_points, 2)`): + Input 2D spatial points, this is used by the prompt encoder to encode the prompt. Generally yields to much + better results. The points can be obtained by passing a list of list of list to the processor that will + create corresponding `torch` tensors of dimension 4. The first dimension is the image batch size, the + second dimension is the point batch size (i.e. how many segmentation masks do we want the model to predict + per input point), the third dimension is the number of points per segmentation mask (it is possible to pass + multiple points for a single mask), and the last dimension is the x (vertical) and y (horizontal) + coordinates of the point. If a different number of points is passed either for each image, or for each + mask, the processor will create "PAD" points that will correspond to the (0, 0) coordinate, and the + computation of the embedding will be skipped for these points using the labels. + input_labels (`torch.LongTensor` of shape `(batch_size, point_batch_size, num_points)`): + Input labels for the points, this is used by the prompt encoder to encode the prompt. According to the + official implementation, there are 3 types of labels + + - `1`: the point is a point that contains the object of interest + - `0`: the point is a point that does not contain the object of interest + - `-1`: the point corresponds to the background + + We added the label: + + - `-10`: the point is a padding point, thus should be ignored by the prompt encoder + + The padding labels should be automatically done by the processor. + input_boxes (`torch.FloatTensor` of shape `(batch_size, num_boxes, 4)`): + Input boxes for the points, this is used by the prompt encoder to encode the prompt. Generally yields to + much better generated masks. The boxes can be obtained by passing a list of list of list to the processor, + that will generate a `torch` tensor, with each dimension corresponding respectively to the image batch + size, the number of boxes per image and the coordinates of the top left and bottom right point of the box. + In the order (`x1`, `y1`, `x2`, `y2`): + + - `x1`: the x coordinate of the top left point of the input box + - `y1`: the y coordinate of the top left point of the input box + - `x2`: the x coordinate of the bottom right point of the input box + - `y2`: the y coordinate of the bottom right point of the input box + input_masks (`torch.FloatTensor` of shape `(batch_size, image_size, image_size)`): + SAM model also accepts segmentation masks as input. The mask will be embedded by the prompt encoder to + generate a corresponding embedding, that will be fed later on to the mask decoder. These masks needs to be + manually fed by the user, and they need to be of shape (`batch_size`, `image_size`, `image_size`). + image_embeddings (`torch.FloatTensor` of shape `(batch_size, output_channels, window_size, window_size)`): + Image embeddings, this is used by the mask decoder to generate masks and iou scores. For more memory + efficient computation, users can first retrieve the image embeddings using the `get_image_embeddings` + method, and then feed them to the `forward` method instead of feeding the `pixel_values`. + multimask_output (`bool`, *optional*): + In the original implementation and paper, the model always outputs 3 masks per image (or per point / per + bounding box if relevant). However, it is possible to just output a single mask, that corresponds to the + "best" mask, by specifying `multimask_output=False`. + attention_similarity (`torch.FloatTensor`, *optional*): + Attention similarity tensor, to be provided to the mask decoder for target-guided attention in case the + model is used for personalization as introduced in [PerSAM](https://huggingface.co/papers/2305.03048). + target_embedding (`torch.FloatTensor`, *optional*): + Embedding of the target concept, to be provided to the mask decoder for target-semantic prompting in case + the model is used for personalization as introduced in [PerSAM](https://huggingface.co/papers/2305.03048). + """ + if not ((pixel_values is None) ^ (image_embeddings is None)): + raise ValueError("Exactly one of pixel_values or image_embeddings must be provided.") + if input_points is not None and input_boxes is not None: + if input_points.shape[1] != input_boxes.shape[1]: + raise ValueError( + f"You should provide as many bounding boxes as input points per box. Got {input_points.shape[1]} and {input_boxes.shape[1]}." + ) + elif input_points is not None: + num_objects = input_points.shape[1] + elif input_boxes is not None: + num_objects = input_boxes.shape[1] + elif input_masks is not None: + num_objects = input_masks.shape[1] + else: + num_objects = 1 + + image_positional_embeddings = self.get_image_wide_positional_embeddings() + # repeat with batch size + batch_size = pixel_values.shape[0] if pixel_values is not None else image_embeddings[-1].shape[0] + image_positional_embeddings = image_positional_embeddings.repeat(batch_size, 1, 1, 1) + + vision_attentions = None + vision_hidden_states = None + + if pixel_values is not None: + image_outputs = self.get_image_features(pixel_values, return_dict=True, **kwargs) + feature_maps = image_outputs.fpn_hidden_states + vision_hidden_states = image_outputs.hidden_states + vision_attentions = image_outputs.attentions + + # add no memory embedding to the last feature map + feature_maps[-1] = feature_maps[-1] + self.no_memory_embedding + + # reshape feature maps to the same shape as the backbone feature sizes + image_embeddings = [ + feat.permute(1, 2, 0).view(batch_size, -1, *feat_size) + for feat, feat_size in zip(feature_maps, self.backbone_feature_sizes) + ] + + if input_points is not None and input_labels is None: + input_labels = torch.ones_like(input_points[:, :, :, 0], dtype=torch.int, device=input_points.device) + + if input_points is None and input_boxes is None: + # If no points are provide, pad with an empty point (with label -1) + input_points = torch.zeros( + batch_size, 1, 1, 2, dtype=image_embeddings[-1].dtype, device=image_embeddings[-1].device + ) + input_labels = -torch.ones(batch_size, 1, 1, dtype=torch.int32, device=image_embeddings[-1].device) + + if input_masks is not None: + # If mask_inputs is provided, downsize it into low-res mask input if needed + # and feed it as a dense mask prompt into the SAM mask encoder + if input_masks.shape[-2:] != self.prompt_encoder.mask_input_size: + input_masks = F.interpolate( + input_masks.float(), + size=self.prompt_encoder.mask_input_size, + align_corners=False, + mode="bilinear", + antialias=True, # use antialias for downsampling + ).to(input_masks.dtype) + + sparse_embeddings, dense_embeddings = self.prompt_encoder( + input_points=input_points, + input_labels=input_labels, + input_boxes=input_boxes, + input_masks=input_masks, + ) + low_res_multimasks, iou_scores, sam_output_tokens, object_score_logits = self.mask_decoder( + image_embeddings=image_embeddings[-1], + image_positional_embeddings=image_positional_embeddings, + sparse_prompt_embeddings=sparse_embeddings, + dense_prompt_embeddings=dense_embeddings, + multimask_output=multimask_output, + high_resolution_features=image_embeddings[:-1], + attention_similarity=attention_similarity, + target_embedding=target_embedding, + **kwargs, + ) + + is_obj_appearing = object_score_logits > 0 + # Mask used for spatial memories is always a *hard* choice between obj and no obj, + # consistent with the actual mask prediction + low_res_multimasks = torch.where( + is_obj_appearing[:, None, None], + low_res_multimasks, + NO_OBJ_SCORE, + ) + + # convert masks from possibly bfloat16 (or float16) to float32 + # (older PyTorch versions before 2.1 don't support `interpolate` on bf16) + high_res_multimasks = ( + F.interpolate( + low_res_multimasks.squeeze(1).float(), + size=(self.image_size, self.image_size), + mode="bilinear", + align_corners=False, + ) + .unsqueeze(1) + .to(low_res_multimasks.dtype) + ) + sam_output_token = sam_output_tokens[:, :, 0] + if multimask_output: + # take the best mask prediction (with the highest IoU estimation) + best_iou_inds = torch.argmax(iou_scores, dim=-1) + batch_inds = torch.arange(batch_size, device=high_res_multimasks.device) + object_batch_inds = torch.arange(num_objects, device=high_res_multimasks.device) + low_res_masks = low_res_multimasks[batch_inds, object_batch_inds, best_iou_inds] + high_res_masks = high_res_multimasks[batch_inds, object_batch_inds, best_iou_inds] + if sam_output_tokens.size(2) > 1: + sam_output_token = sam_output_tokens[batch_inds, object_batch_inds, best_iou_inds] + else: + low_res_masks, high_res_masks = low_res_multimasks[:, :, 0], high_res_multimasks[:, :, 0] + + # Extract object pointer from the SAM output token (with occlusion handling) + object_pointer = self.object_pointer_proj(sam_output_token) + lambda_is_obj_appearing = is_obj_appearing.to(object_pointer.dtype) + + object_pointer = lambda_is_obj_appearing * object_pointer + object_pointer = object_pointer + (1 - lambda_is_obj_appearing) * self.no_object_pointer + + return Sam3TrackerVideoImageSegmentationOutput( + iou_scores=iou_scores, + pred_masks=low_res_masks, + high_res_masks=high_res_masks, + object_pointer=object_pointer, + object_score_logits=object_score_logits, + image_embeddings=image_embeddings, + vision_hidden_states=vision_hidden_states, + vision_attentions=vision_attentions, + ) + + def _use_mask_as_output( + self, + backbone_features: torch.Tensor, + high_res_features: list[torch.Tensor], + mask_inputs: torch.Tensor, + ) -> Sam3TrackerVideoImageSegmentationOutput: + """ + Directly turn binary `mask_inputs` into a output mask logits without using SAM. + (same input and output shapes as in forward above). + """ + # Use -10/+20 as logits for neg/pos pixels (very close to 0/1 in prob after sigmoid). + out_scale, out_bias = 20.0, -10.0 # sigmoid(-10.0)=4.5398e-05 + mask_inputs_float = mask_inputs.to(backbone_features[0].dtype) + + # Ensure mask is at self.image_size resolution for consistency + if mask_inputs_float.shape[-2:] != (self.image_size, self.image_size): + mask_inputs_float = F.interpolate( + mask_inputs_float.float(), + size=(self.image_size, self.image_size), + align_corners=False, + mode="bilinear", + antialias=True, + ).to(mask_inputs.dtype) + + high_res_masks = mask_inputs_float * out_scale + out_bias + low_res_masks = F.interpolate( + high_res_masks.float(), + size=self.prompt_encoder.mask_input_size, + align_corners=False, + mode="bilinear", + antialias=True, # use antialias for downsampling + ).to(backbone_features[0].dtype) + # a dummy IoU prediction of all 1's under mask input + iou_scores = mask_inputs.new_ones(mask_inputs.size(0), 1).to(backbone_features[0].dtype) + # produce an object pointer using the SAM decoder from the mask input + object_pointer = self._single_frame_forward( + input_masks=self.mask_downsample(mask_inputs_float.to(backbone_features[0].dtype)), + image_embeddings=high_res_features + [backbone_features], + ).object_pointer + # In this method, we are treating mask_input as output, e.g. using it directly to create spatial mem; + # Below, we follow the same design axiom to use mask_input to decide if obj appears or not instead of relying + # on the object_scores from the SAM decoder. + is_obj_appearing = torch.any(mask_inputs.flatten(1).float() > 0.0, dim=1) + is_obj_appearing = is_obj_appearing[..., None] + lambda_is_obj_appearing = is_obj_appearing.to(backbone_features[0].dtype) + object_score_logits = out_scale * lambda_is_obj_appearing + out_bias + object_pointer = lambda_is_obj_appearing * object_pointer + object_pointer = object_pointer + (1 - lambda_is_obj_appearing) * self.no_object_pointer + return Sam3TrackerVideoImageSegmentationOutput( + iou_scores=iou_scores, + pred_masks=low_res_masks, + high_res_masks=high_res_masks, + object_pointer=object_pointer, + object_score_logits=object_score_logits.unsqueeze(-1), + image_embeddings=high_res_features + [backbone_features], + ) + + def _select_closest_cond_frames(self, frame_idx, cond_frame_outputs, max_cond_frame_num): + """ + Select up to `max_cond_frame_num` conditioning frames from `cond_frame_outputs` + that are temporally closest to the current frame at `frame_idx`. Here, we take + - a) the closest conditioning frame before `frame_idx` (if any); + - b) the closest conditioning frame after `frame_idx` (if any); + - c) any other temporally closest conditioning frames until reaching a total + of `max_cond_frame_num` conditioning frames. + + Outputs: + - selected_outputs: selected items (keys & values) from `cond_frame_outputs`. + - unselected_outputs: items (keys & values) not selected in `cond_frame_outputs`. + """ + if max_cond_frame_num == -1 or len(cond_frame_outputs) <= max_cond_frame_num: + selected_outputs = cond_frame_outputs + unselected_outputs = {} + else: + selected_outputs = {} + # the closest conditioning frame before `frame_idx` (if any) + idx_before = max((t for t in cond_frame_outputs if t < frame_idx), default=None) + if idx_before is not None: + selected_outputs[idx_before] = cond_frame_outputs[idx_before] + + # the closest conditioning frame after `frame_idx` (if any) + idx_after = min((t for t in cond_frame_outputs if t >= frame_idx), default=None) + if idx_after is not None: + selected_outputs[idx_after] = cond_frame_outputs[idx_after] + + # add other temporally closest conditioning frames until reaching a total + # of `max_cond_frame_num` conditioning frames. + num_remain = max_cond_frame_num - len(selected_outputs) + inds_remain = sorted( + (t for t in cond_frame_outputs if t not in selected_outputs), + key=lambda x: abs(x - frame_idx), + )[:num_remain] + selected_outputs.update((t, cond_frame_outputs[t]) for t in inds_remain) + unselected_outputs = {t: v for t, v in cond_frame_outputs.items() if t not in selected_outputs} + + return selected_outputs, unselected_outputs + + def _gather_memory_frame_outputs( + self, + inference_session: Sam3TrackerVideoInferenceSession, + obj_idx: int, + frame_idx: int, + track_in_reverse_time: bool = False, + ) -> list[tuple[int, dict]]: + """ + Get memory frames from conditioning and non-conditioning outputs. + + Returns: + List of (relative_temporal_offset, output_data) tuples. + """ + temporal_positions_and_previous_outputs = [] + + # Add conditioning frame outputs (limited by max_cond_frame_num) + conditioning_outputs = inference_session.output_dict_per_obj[obj_idx]["cond_frame_outputs"] + if not conditioning_outputs: + raise ValueError( + "maskmem_features in conditioning outputs cannot be empty when not is_initial_conditioning_frame" + ) + conditioning_outputs, unselected_conditioning_outputs = self._select_closest_cond_frames( + frame_idx, conditioning_outputs, max_cond_frame_num=self.config.max_cond_frame_num + ) + + # Store (temporal_position, output_data) tuples + temporal_positions_and_previous_outputs = [(0, out) for out in conditioning_outputs.values()] + + # Add non-conditioning memory frames (up to self.num_maskmem - 1) + # These are typically frames tracked by the model without direct user input. + # Frames are selected with a stride, prioritizing the most recent ones. Here we only support stride = 1 for simplicity. + for relative_temporal_offset in range(self.num_maskmem - 1, 0, -1): + # relative_temporal_offset: how many frames before (or after if reversing) the current frame + if not track_in_reverse_time: + previous_frame_idx = frame_idx - relative_temporal_offset + else: + previous_frame_idx = frame_idx + relative_temporal_offset + + # check if the output is already stored without using get_output to avoid unnecessary memory transfers between CPU and GPU + output_data = inference_session.output_dict_per_obj[obj_idx]["non_cond_frame_outputs"].get( + previous_frame_idx, unselected_conditioning_outputs.get(previous_frame_idx, None) + ) + + temporal_positions_and_previous_outputs.append((relative_temporal_offset, output_data)) + + return temporal_positions_and_previous_outputs + + def _build_memory_attention_inputs( + self, + temporal_positions_and_previous_outputs: list[tuple[int, dict]], + device: torch.device, + ) -> tuple[list[torch.Tensor], list[torch.Tensor]]: + """ + Concatenate memory features and positional embeddings from previous frames. + + Returns: + Tuple of (memories_to_concatenate, memory_positional_embeddings_to_concatenate). + """ + memories_to_concatenate = [] + memory_positional_embeddings_to_concatenate = [] + + for relative_temporal_offset, prev_output_data in temporal_positions_and_previous_outputs: + if prev_output_data is None: + continue # Skip if no output data for this temporal position (e.g., padding frames) + + # Load memory features (potentially from CPU to GPU) + # Features are flattened: (Batch, Channels, H, W) -> (H*W, Batch, Channels) + memory_features = prev_output_data["maskmem_features"].to(device, non_blocking=True) + memories_to_concatenate.append(memory_features) + + # Spatial positional encoding (potentially from CPU to GPU) + spatial_memory_pos_embed = prev_output_data["maskmem_pos_enc"].to(device, non_blocking=True) + + # Add temporal positional encoding + # self.memory_temporal_positional_encoding shape: (NumMaskMem, 1, 1, MemDim) + combined_memory_pos_embed = ( + spatial_memory_pos_embed + self.memory_temporal_positional_encoding[relative_temporal_offset - 1] + ) + memory_positional_embeddings_to_concatenate.append(combined_memory_pos_embed) + + return memories_to_concatenate, memory_positional_embeddings_to_concatenate + + def _get_object_pointers( + self, + inference_session: Sam3TrackerVideoInferenceSession, + obj_idx: int, + frame_idx: int, + num_total_frames: int, + device: torch.device, + track_in_reverse_time: bool = False, + streaming: bool = False, + ) -> tuple[list[int], list[torch.Tensor], int]: + """ + Get object pointers and their positional embeddings from past frames. + + Returns: + Tuple of (temporal_offsets, pointer_tokens, max_object_pointers_to_use). + """ + temporal_position_sign_multiplier = -1 if track_in_reverse_time else 1 + + # Determine max object pointers to use + if streaming: + max_object_pointers_to_use = self.config.max_object_pointers_in_encoder + else: + max_object_pointers_to_use = min(num_total_frames, self.config.max_object_pointers_in_encoder) + + temporal_offsets: list[int] = [] + pointer_tokens: list[torch.Tensor] = [] + + # Add object pointers from selected conditioning frames + # Optionally, only include pointers from past frames during evaluation + conditioning_outputs = inference_session.output_dict_per_obj[obj_idx]["cond_frame_outputs"] + eligible_conditioning_outputs = conditioning_outputs + if not self.training: + eligible_conditioning_outputs = { + temporal_idx: out + for temporal_idx, out in conditioning_outputs.items() + if (temporal_idx >= frame_idx if track_in_reverse_time else temporal_idx <= frame_idx) + } + + for temporal_idx, out_data in eligible_conditioning_outputs.items(): + temporal_difference = (frame_idx - temporal_idx) * temporal_position_sign_multiplier + temporal_offsets.append(temporal_difference) + pointer_tokens.append(out_data["object_pointer"].to(device)) + + # Add object pointers from non-conditioning frames (up to max_object_pointers_to_use - 1) + for t_diff_offset in range(1, max_object_pointers_to_use): + ref_frame_idx = frame_idx + t_diff_offset if track_in_reverse_time else frame_idx - t_diff_offset + if ref_frame_idx < 0 or ( + not streaming and num_total_frames is not None and ref_frame_idx >= num_total_frames + ): + break # Stop if frame index is out of bounds + + # check if the output is already stored without using get_output to avoid unnecessary memory transfers between CPU and GPU + out_data = inference_session.output_dict_per_obj[obj_idx]["non_cond_frame_outputs"].get( + ref_frame_idx, None + ) + if out_data is not None: + temporal_offsets.append(t_diff_offset) + pointer_tokens.append(out_data["object_pointer"].to(device)) + + return temporal_offsets, pointer_tokens, max_object_pointers_to_use + + def _process_object_pointers( + self, + temporal_offsets: list[int], + pointer_tokens: list[torch.Tensor], + max_object_pointers_to_use: int, + batch_size: int, + num_channels: int, + device: torch.device, + ) -> tuple[torch.Tensor, torch.Tensor]: + """ + Process object pointers and compute their positional embeddings. + + Returns: + Tuple of (object_pointers, object_pointers_pos_embed). + """ + if not pointer_tokens: + return None, None + + # Stack object pointers: List of (Batch, Channels) -> (SeqLen_ptr, Batch, Channels) + object_pointers = torch.stack(pointer_tokens, dim=0) + + if self.config.enable_temporal_pos_encoding_for_object_pointers: + max_temporal_diff = float(max_object_pointers_to_use - 1) + # Determine dimensionality for temporal positional encoding of pointers + pointer_tpos_dim = num_channels + + # Normalize temporal differences before sine PE calculation + normalized_temporal_diffs = ( + torch.tensor(temporal_offsets, device=device, dtype=torch.float32) / max_temporal_diff + ) + sine_pe = get_1d_sine_pe(normalized_temporal_diffs, dim=pointer_tpos_dim).to(object_pointers.dtype) + projected_sine_pe = self.temporal_positional_encoding_projection_layer(sine_pe) + object_pointers_pos_embed = projected_sine_pe.unsqueeze(1).expand(-1, batch_size, self.mem_dim) + else: + object_pointers_pos_embed = object_pointers.new_zeros( + len(temporal_offsets), batch_size, self.mem_dim, dtype=object_pointers.dtype + ) + + if self.mem_dim < num_channels: + # If memory dimension is smaller, reshape/split pointers and repeat positional encoding + num_splits = num_channels // self.mem_dim + object_pointers = object_pointers.reshape(-1, batch_size, num_splits, self.mem_dim) + object_pointers = object_pointers.permute(0, 2, 1, 3).flatten( + 0, 1 + ) # (SeqLen_ptr*num_splits, Batch, MemDim) + object_pointers_pos_embed = object_pointers_pos_embed.repeat_interleave(num_splits, dim=0) + + return object_pointers, object_pointers_pos_embed + + def _prepare_memory_conditioned_features( + self, + inference_session: Sam3TrackerVideoInferenceSession, + frame_idx: int, + obj_idx: int, + is_initial_conditioning_frame: bool, + current_vision_features: list[torch.Tensor], + current_vision_positional_embeddings: list[torch.Tensor], + num_total_frames: int, + track_in_reverse_time: bool = False, + streaming: bool = False, + ) -> torch.Tensor: + """ + Fuse current frame's visual features with memory from previous frames for enhanced object tracking. + + This method conditions the current frame's visual features on temporal memory from previous frames, + enabling consistent object tracking across video sequences. For initial conditioning frames, it uses + no-memory embeddings. For subsequent frames, it retrieves and integrates memory features from both + conditioning frames (user interactions) and non-conditioning frames (tracked results) via cross-attention. + + Args: + inference_session (`Sam3TrackerVideoInferenceSession`): + The video inference session object. + frame_idx (`int`): + Index of the current frame being processed. + obj_idx (`int`): + Index of the object being processed. + is_initial_conditioning_frame (`bool`): + Whether this is an initial conditioning frame with user inputs (True) or a subsequent + tracking frame (False). + current_vision_features (`torch.Tensor`): + Highest-level vision features of shape `(seq_len, batch_size, channels)`. + current_vision_positional_embeddings (`torch.Tensor`): + Positional embedding tensors corresponding to the highest-level vision features. + num_total_frames (`int`): + Total number of frames in the video sequence. + track_in_reverse_time (`bool`, *optional*, defaults to `False`): + Whether tracking is performed in reverse temporal order. + streaming (`bool`, *optional*, defaults to `False`): + Whether this is streaming inference mode. + + Returns: + `torch.Tensor`: Memory-conditioned feature tensor of shape `(batch_size, channels, height, width)` + suitable for input to the SAM decoder. + """ + # Get dimensions from the highest-level (lowest-resolution) feature map + batch_size = current_vision_features.size(1) + num_channels = self.hidden_dim + height, width = self.backbone_feature_sizes[-1] + device = current_vision_features.device + + # If memory is disabled (e.g., for single image SAM), return current features directly. + if self.num_maskmem == 0: + # Permute (SeqLen, Batch, Channels) -> (Batch, Channels, SeqLen) then view as (Batch, Channels, Height, Width) + # Assuming SeqLen = Height * Width for the last feature map + current_feature_map = current_vision_features.permute(1, 2, 0).view( + batch_size, num_channels, height, width + ) + return current_feature_map + + # Step 1: Handle initial conditioning frames + if is_initial_conditioning_frame: + # For initial conditioning frames, no prior memory is used directly in this block. + # If configured, directly add a learnable "no memory" embedding. + # current_vision_features has shape (SeqLen, Batch, Channels) + conditioned_feature_map_flat = current_vision_features + self.no_memory_embedding + # Reshape to (Batch, Channels, Height, Width) + conditioned_feature_map = conditioned_feature_map_flat.permute(1, 2, 0).view( + batch_size, num_channels, height, width + ) + return conditioned_feature_map + + # Step 2: Get memory frames and concatenate their features + temporal_positions_and_previous_outputs = self._gather_memory_frame_outputs( + inference_session, obj_idx, frame_idx, track_in_reverse_time + ) + + memories_to_concatenate, memory_positional_embeddings_to_concatenate = self._build_memory_attention_inputs( + temporal_positions_and_previous_outputs, device + ) + + # Step 3: Get and process object pointers + temporal_offsets, pointer_tokens, max_object_pointers_to_use = self._get_object_pointers( + inference_session, obj_idx, frame_idx, num_total_frames, device, track_in_reverse_time, streaming + ) + + num_object_pointer_tokens = 0 + if pointer_tokens: + object_pointers, object_pointers_pos_embed = self._process_object_pointers( + temporal_offsets, pointer_tokens, max_object_pointers_to_use, batch_size, num_channels, device + ) + + if object_pointers is not None: + memories_to_concatenate.append(object_pointers) + memory_positional_embeddings_to_concatenate.append(object_pointers_pos_embed) + num_object_pointer_tokens = object_pointers.shape[0] + + # Step 4: Concatenate all retrieved memories and their positional embeddings + combined_memory = torch.cat(memories_to_concatenate, dim=0).to(dtype=inference_session.dtype) + combined_memory_positional_embeddings = torch.cat(memory_positional_embeddings_to_concatenate, dim=0) + + # Step 5: Forward through the memory attention mechanism + conditioned_feature_map_flat = self.memory_attention( + current_vision_features=current_vision_features, + current_vision_position_embeddings=current_vision_positional_embeddings, + memory=combined_memory, + memory_posision_embeddings=combined_memory_positional_embeddings, # Corrected typo from API + num_object_pointer_tokens=num_object_pointer_tokens, + ) + + # Reshape from (Batch, H*W, Channels) to (Batch, Channels, Height, Width) + conditioned_feature_map = ( + conditioned_feature_map_flat.squeeze(1).permute(0, 2, 1).view(batch_size, num_channels, height, width) + ) + return conditioned_feature_map + + def _use_multimask(self, is_init_cond_frame: bool, point_inputs: dict | None) -> bool: + """Whether to use multimask output in the SAM head.""" + num_pts = 0 if point_inputs is None else point_inputs["point_labels"].size(2) + multimask_output = ( + self.config.multimask_output_in_sam + and (is_init_cond_frame or self.config.multimask_output_for_tracking) + and (self.config.multimask_min_pt_num <= num_pts <= self.config.multimask_max_pt_num) + ) + return multimask_output + + def _run_single_frame_inference( + self, + inference_session: Sam3TrackerVideoInferenceSession, + frame_idx: int, + obj_idx: int, + batch_size: int, + is_init_cond_frame: bool, + point_inputs: torch.Tensor | None, + mask_inputs: torch.Tensor | None, + reverse: bool, + prev_sam_mask_logits: torch.Tensor | None = None, + streaming: bool = False, + ) -> dict[str, Any]: + """ + Perform a single tracking step for video object segmentation. + + Args: + inference_session (`Sam3TrackerVideoInferenceSession`): + The video inference session object. + frame_idx (`int`): + Index of the current frame. + obj_idx (`int`): + Index of the current object. + batch_size (`int`): + Batch size of the current frame. + is_init_cond_frame (`bool`): + Whether this is an initial conditioning frame with user inputs. + point_inputs (`dict`, *optional*): + Point prompt inputs for the current frame. + mask_inputs (`torch.Tensor`, *optional*): + Mask prompt inputs for the current frame. + reverse (`bool`, *optional*, defaults to `False`): + Whether to track in reverse time order. + prev_sam_mask_logits (`torch.Tensor`, *optional*): + Previously predicted SAM mask logits that can be fed with new clicks. + streaming (`bool`, *optional*, defaults to `False`): + Whether this is streaming inference. + + Returns: + `dict`: Dictionary containing the tracking results for the current frame, including: + - pred_masks: Predicted low-resolution masks. + - object_pointer: Object pointer for memory. + - high_res_masks: High-resolution masks for batched memory encoding. + - object_score_logits: Object score logits (inference only). + """ + # Retrieve correct image features + current_vision_feats, current_vision_pos_embeds = self._prepare_vision_features( + inference_session, frame_idx, batch_size + ) + # point and mask should not appear as input simultaneously on the same frame + if point_inputs is not None and mask_inputs is not None: + raise ValueError( + "point_inputs and mask_inputs should not appear as input simultaneously on the same frame" + ) + # High-resolution feature maps for the SAM head, reshape (HW)BC => BCHW + if len(current_vision_feats) > 1: + high_res_features = [ + x.permute(1, 2, 0).view(x.size(1), x.size(2), *s) + for x, s in zip(current_vision_feats[:-1], self.backbone_feature_sizes[:-1]) + ] + else: + high_res_features = None + if mask_inputs is not None: + # We directly output the mask input (see it as a GT mask) without using a SAM prompt encoder + mask decoder. + pix_feat = current_vision_feats[-1].permute(1, 2, 0) + pix_feat = pix_feat.view(-1, self.hidden_dim, *self.backbone_feature_sizes[-1]) + sam_outputs = self._use_mask_as_output(pix_feat, high_res_features, mask_inputs) + else: + # fused the visual feature with previous memory features in the memory bank + pix_feat = self._prepare_memory_conditioned_features( + inference_session=inference_session, + frame_idx=frame_idx, + obj_idx=obj_idx, + is_initial_conditioning_frame=is_init_cond_frame, + current_vision_features=current_vision_feats[-1], + current_vision_positional_embeddings=current_vision_pos_embeds[-1], + num_total_frames=inference_session.num_frames, + track_in_reverse_time=reverse, + streaming=streaming, + ) + # apply SAM-style segmentation head + # here we might feed previously predicted low-res SAM mask logits into the SAM mask decoder, + # e.g. in demo where such logits come from earlier interaction instead of correction sampling + # (in this case, any `mask_inputs` shouldn't reach here as they are sent to _use_mask_as_output instead) + if prev_sam_mask_logits is not None: + mask_inputs = prev_sam_mask_logits + multimask_output = self._use_multimask(is_init_cond_frame, point_inputs) + sam_outputs = self._single_frame_forward( + pixel_values=None, # Vision features already computed + input_points=point_inputs["point_coords"] if point_inputs is not None else None, + input_labels=point_inputs["point_labels"] if point_inputs is not None else None, + input_masks=mask_inputs, + image_embeddings=high_res_features + [pix_feat], + multimask_output=multimask_output, + ) + + # Memory encoding is now handled in batch by the caller (forward method) + current_out = { + "pred_masks": sam_outputs.pred_masks, + "object_pointer": sam_outputs.object_pointer, + "high_res_masks": sam_outputs.high_res_masks, # Needed for batched memory encoding + } + if not self.training: + current_out["object_score_logits"] = sam_outputs.object_score_logits + + return current_out + + def _encode_new_memory( + self, + current_vision_feats: torch.Tensor, + pred_masks_high_res: torch.Tensor, + object_score_logits: torch.Tensor, + is_mask_from_pts: bool, + ) -> tuple[torch.Tensor, list[torch.Tensor]]: + """Encode the current image and its prediction into a memory feature.""" + batch_size = current_vision_feats.size(1) # batch size on this frame + channels = self.hidden_dim + height, width = self.backbone_feature_sizes[-1] # top-level (lowest-resolution) feature size + + mask_input_size_h, mask_input_size_w = self.prompt_encoder.mask_input_size + mask_mem_size_h = mask_input_size_h * 4 + mask_mem_size_w = mask_input_size_w * 4 + if pred_masks_high_res.shape[2:] != (mask_mem_size_h, mask_mem_size_w): + # downsample the predicted high-res masks into the mask encoder input size + pred_masks_high_res = F.interpolate( + pred_masks_high_res.float(), + size=(mask_mem_size_h, mask_mem_size_w), + align_corners=False, + mode="bilinear", + antialias=True, # use antialias for downsampling + ).to(pred_masks_high_res.dtype) + + # top-level feature, (HW)BC => BCHW + pix_feat = current_vision_feats.permute(1, 2, 0).view(batch_size, channels, height, width) + if is_mask_from_pts and not self.training: + # binarize the mask logits + mask_for_mem = (pred_masks_high_res > 0).to(pred_masks_high_res.dtype) + else: + # apply sigmoid on the raw mask logits to turn them into range (0, 1) + mask_for_mem = torch.sigmoid(pred_masks_high_res) + # apply scale and bias terms to the sigmoid probabilities + mask_for_mem = mask_for_mem * self.config.sigmoid_scale_for_mem_enc + mask_for_mem = mask_for_mem + self.config.sigmoid_bias_for_mem_enc + + maskmem_features, maskmem_pos_enc = self.memory_encoder( + pix_feat, + mask_for_mem, + ) + # add a no-object embedding to the spatial memory to indicate that the frame + # is predicted to be occluded (i.e. no object is appearing in the frame) + if self.occlusion_spatial_embedding_parameter is not None: + is_obj_appearing = (object_score_logits > 0).float() + maskmem_features += (1 - is_obj_appearing[..., None]) * self.occlusion_spatial_embedding_parameter[ + ..., None, None + ].expand(*maskmem_features.shape) + + # convert to bfloat16 to save memory, and for consistency with the original implementation + maskmem_features = maskmem_features.to(torch.bfloat16).flatten(2).permute(2, 0, 1) + maskmem_pos_enc = maskmem_pos_enc.to(pred_masks_high_res.dtype).flatten(2).permute(2, 0, 1) + + return maskmem_features, maskmem_pos_enc + + def _batch_encode_memories( + self, + inference_session: Sam3TrackerVideoInferenceSession, + frame_idx: int, + objects_needing_memory_encoding: list[int], + high_res_masks_for_memory: list[torch.Tensor], + object_score_logits_for_memory: list[torch.Tensor], + is_mask_from_pts_per_obj: list[bool], + ): + """ + Batch encode memories for multiple objects at once. + + Args: + inference_session: The video inference session object + frame_idx: Index of the current frame + objects_needing_memory_encoding: List of object indices that need memory encoding + high_res_masks_for_memory: List of high-resolution masks for each object + object_score_logits_for_memory: List of object score logits for each object + is_mask_from_pts_per_obj: List of booleans indicating if mask is from points for each object + """ + if not objects_needing_memory_encoding: + return + + # Get vision features once for all objects + current_vision_feats, _ = self._prepare_vision_features(inference_session, frame_idx, batch_size=1) + + # Stack all high-res masks and object scores + high_res_masks_batched = torch.cat(high_res_masks_for_memory, dim=0) + object_score_logits_batched = torch.cat(object_score_logits_for_memory, dim=0) + + # Expand vision features to match batch size + expanded_vision_feats = current_vision_feats[-1].expand(-1, len(objects_needing_memory_encoding), -1) + + # Encode all memories in one batch call + maskmem_features_batched, maskmem_pos_enc_batched = self._encode_new_memory( + current_vision_feats=expanded_vision_feats, + pred_masks_high_res=high_res_masks_batched, + object_score_logits=object_score_logits_batched, + is_mask_from_pts=any(is_mask_from_pts_per_obj), + ) + + # Split and store encoded memories per object + for i, obj_idx in enumerate(objects_needing_memory_encoding): + # Extract per-object memory from batched result + maskmem_features = maskmem_features_batched[:, i : i + 1] + maskmem_pos_enc = maskmem_pos_enc_batched[:, i : i + 1] + + # Update the stored output with memory features + output_dict = inference_session.output_dict_per_obj[obj_idx] + # Determine if this was a conditioning frame + storage_key = ( + "cond_frame_outputs" if frame_idx in output_dict["cond_frame_outputs"] else "non_cond_frame_outputs" + ) + if frame_idx in output_dict[storage_key]: + output_dict[storage_key][frame_idx]["maskmem_features"] = maskmem_features + output_dict[storage_key][frame_idx]["maskmem_pos_enc"] = maskmem_pos_enc + + @torch.inference_mode() + @auto_docstring( + custom_intro=""" + Propagate the objects through the video frames. Used when initializing an inference session with a whole video. + Yields Sam3TrackerVideoSegmentationOutput for each frame. + """ + ) + def propagate_in_video_iterator( + self, + inference_session: Sam3TrackerVideoInferenceSession, + start_frame_idx: int | None = None, + max_frame_num_to_track: int | None = None, + reverse: bool = False, + show_progress_bar: bool = False, + ) -> Iterator[Sam3TrackerVideoSegmentationOutput]: + r""" + inference_session (`Sam3TrackerVideoInferenceSession`): + The video inference session object. + start_frame_idx (`int`, *optional*): + The starting frame index for propagation. + Need to be provided if `forward` hasn't been called on new inputs yet. + If not provided, the starting frame index will be the earliest frame with input points. + max_frame_num_to_track (`int`, *optional*): + The maximum number of frames to track. + reverse (`bool`, *optional*, defaults to `False`): + Whether to propagate in reverse. + show_progress_bar (`bool`, *optional*, defaults to `False`): + Whether to show a progress bar during propagation. + """ + num_frames = inference_session.num_frames + + # set start index, end index, and processing order + if start_frame_idx is None: + # default: start from the earliest frame with input points + frames_with_inputs = [ + frame_idx + for obj_output_dict in inference_session.output_dict_per_obj.values() + for frame_idx in obj_output_dict["cond_frame_outputs"] + ] + if not frames_with_inputs: + raise ValueError( + "Cannot determine the starting frame index; please specify it manually, or run inference on a frame with inputs first." + ) + start_frame_idx = min(frames_with_inputs) + if max_frame_num_to_track is None: + # default: track all the frames in the video + max_frame_num_to_track = num_frames + if reverse: + end_frame_idx = max(start_frame_idx - max_frame_num_to_track, 0) + if start_frame_idx > 0: + processing_order = range(start_frame_idx, end_frame_idx - 1, -1) + else: + processing_order = [] # skip reverse tracking if starting from frame 0 + else: + end_frame_idx = min(start_frame_idx + max_frame_num_to_track, num_frames - 1) + processing_order = range(start_frame_idx, end_frame_idx + 1) + + for frame_idx in tqdm(processing_order, desc="propagate in video", disable=not show_progress_bar): + sam3_tracker_video_output = self(inference_session, frame_idx=frame_idx, reverse=reverse) + yield sam3_tracker_video_output + + +__all__ = ["Sam3TrackerVideoModel", "Sam3TrackerVideoInferenceSession", "Sam3TrackerVideoPreTrainedModel"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam3_tracker_video/modular_sam3_tracker_video.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam3_tracker_video/modular_sam3_tracker_video.py new file mode 100644 index 0000000000000000000000000000000000000000..1d357fe923b0291ffaced11c0d728deec47cb9df --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam3_tracker_video/modular_sam3_tracker_video.py @@ -0,0 +1,591 @@ +# Copyright 2025 the HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + + +import torch + +from ...configuration_utils import PreTrainedConfig +from ...processing_utils import Unpack +from ...utils import TransformersKwargs, auto_docstring, can_return_tuple +from ..auto import CONFIG_MAPPING, AutoConfig, AutoModel +from ..sam2_video.configuration_sam2_video import Sam2VideoMaskDecoderConfig, Sam2VideoPromptEncoderConfig +from ..sam2_video.modeling_sam2_video import ( + Sam2VideoAttention, + Sam2VideoFeedForward, + Sam2VideoImageSegmentationOutput, + Sam2VideoInferenceCache, + Sam2VideoInferenceSession, + Sam2VideoLayerNorm, + Sam2VideoMaskDecoder, + Sam2VideoMaskDownSampler, + Sam2VideoMaskDownSamplerLayer, + Sam2VideoMaskEmbedding, + Sam2VideoMemoryAttention, + Sam2VideoMemoryAttentionLayer, + Sam2VideoMemoryEncoder, + Sam2VideoMemoryFuser, + Sam2VideoMemoryFuserCXBlock, + Sam2VideoModel, + Sam2VideoPositionalEmbedding, + Sam2VideoPositionEmbeddingSine, + Sam2VideoPreTrainedModel, + Sam2VideoPromptEncoder, + Sam2VideoRoPEAttention, + Sam2VideoSegmentationOutput, + Sam2VideoTwoWayAttentionBlock, + Sam2VideoTwoWayTransformer, + Sam2VideoVisionEncoderOutput, + Sam2VideoVisionRotaryEmbedding, +) +from ..sam2_video.processing_sam2_video import Sam2VideoProcessor + + +class Sam3TrackerVideoPromptEncoderConfig(Sam2VideoPromptEncoderConfig): + r""" + This is the configuration class to store the configuration of a [`Sam3TrackerVideoPromptEncoder`]. The [`Sam3TrackerVideoPromptEncoder`] + module is used to encode the input 2D points and bounding boxes. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + hidden_size (`int`, *optional*, defaults to 256): + Dimensionality of the hidden states. + image_size (`int`, *optional*, defaults to 1008): + The expected output resolution of the image. + patch_size (`int`, *optional*, defaults to 14): + The size (resolution) of each patch. + mask_input_channels (`int`, *optional*, defaults to 16): + The number of channels to be fed to the `MaskDecoder` module. + num_point_embeddings (`int`, *optional*, defaults to 4): + The number of point embeddings to be used. + hidden_act (`str`, *optional*, defaults to `"gelu"`): + The non-linear activation function in the encoder and pooler. + layer_norm_eps (`float`, *optional*, defaults to 1e-06): + The epsilon used by the layer normalization layers. + scale (`float`, *optional*, defaults to 1): + The scale factor for the prompt encoder. + """ + + base_config_key = "prompt_encoder_config" + + def __init__( + self, + hidden_size=256, + image_size=1008, + patch_size=14, + mask_input_channels=16, + num_point_embeddings=4, + hidden_act="gelu", + layer_norm_eps=1e-6, + scale=1, + **kwargs, + ): + super().__init__(**kwargs) + + +class Sam3TrackerVideoProcessor(Sam2VideoProcessor): + pass + + +class Sam3TrackerVideoMaskDecoderConfig(Sam2VideoMaskDecoderConfig): + pass + + +class Sam3TrackerVideoConfig(PreTrainedConfig): + r""" + [`Sam3TrackerVideoConfig`] is the configuration class to store the configuration of a [`Sam3TrackerVideoModel`]. It is used to instantiate a + SAM3 tracker video model according to the specified arguments, defining the memory attention, memory encoder, and image encoder + configs. Instantiating a configuration defaults will yield a similar configuration to that of the SAM 3 + [facebook/sam3](https://huggingface.co/facebook/sam3) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + vision_config (Union[`dict`, `Sam3TrackerVideoVisionConfig`], *optional*): + Dictionary of configuration options used to initialize [`Sam3TrackerVideoVisionConfig`]. + prompt_encoder_config (Union[`dict`, `Sam3TrackerVideoPromptEncoderConfig`], *optional*): + Dictionary of configuration options used to initialize [`Sam3TrackerVideoPromptEncoderConfig`]. + mask_decoder_config (Union[`dict`, `Sam3TrackerVideoMaskDecoderConfig`], *optional*): + Dictionary of configuration options used to initialize [`Sam3TrackerVideoMaskDecoderConfig`]. + initializer_range (`float`, *optional*, defaults to 0.02): + Standard deviation for parameter initialization. + num_maskmem (`int`, *optional*, defaults to 7): + The number of memory slots for the mask memory. + image_size (`int`, *optional*, defaults to 1008): + The size of the input images. + sigmoid_scale_for_mem_enc (`float`, *optional*, defaults to 20.0): + Scale factor for the sigmoid function in the memory encoder. + sigmoid_bias_for_mem_enc (`float`, *optional*, defaults to -10.0): + Bias for the sigmoid function in the memory encoder. + enable_occlusion_spatial_embedding (`bool`, *optional*, defaults to `True`): + Whether to enable spatial embedding for occlusions. + multimask_output_in_sam (`bool`, *optional*, defaults to `True`): + Whether to output multiple masks from the SAM head. + multimask_min_pt_num (`int`, *optional*, defaults to 0): + The minimum number of points to trigger multimask output. + multimask_max_pt_num (`int`, *optional*, defaults to 1): + The maximum number of points to trigger multimask output. + multimask_output_for_tracking (`bool`, *optional*, defaults to `True`): + Whether to use multimask output for tracking. + max_object_pointers_in_encoder (`int`, *optional*, defaults to 16): + The maximum number of object pointers in the encoder. + max_cond_frame_num (`int`, *optional*, defaults to 4): + Maximum number of conditioning frames to use in memory attention. + enable_temporal_pos_encoding_for_object_pointers (`bool`, *optional*, defaults to `True`): + Whether to enable temporal positional encoding for object pointers. + memory_attention_hidden_size (`int`, *optional*, defaults to 256): + Dimensionality of the memory attention hidden states. + memory_attention_num_layers (`int`, *optional*, defaults to 4): + The number of layers in the memory attention module. + memory_attention_num_attention_heads (`int`, *optional*, defaults to 1): + Number of attention heads for each attention layer in the memory attention. + memory_attention_downsample_rate (`int`, *optional*, defaults to 1): + The downsample rate for the attention layers. + memory_attention_feed_forward_hidden_size (`int`, *optional*, defaults to 2048): + The dimension of the feedforward network in the memory attention module. + memory_attention_feed_forward_hidden_act (`str`, *optional*, defaults to `"relu"`): + The non-linear activation function in the feedforward network in the memory attention module. + memory_attention_dropout (`float`, *optional*, defaults to 0.1): + The dropout rate for the memory attention module. + memory_attention_rope_theta (`float`, *optional*, defaults to 10000): + The Rope theta parameter. + memory_attention_rope_feat_sizes (`list[int]`, *optional*, defaults to `[72, 72]`): + The feature sizes for the Rope positional encoding. + memory_attention_rope_dropout (`float`, *optional*, defaults to 0.1): + The dropout rate for the Rope positional encoding. + memory_encoder_hidden_size (`int`, *optional*, defaults to 256): + Dimensionality of the memory encoder hidden states. + memory_encoder_output_channels (`int`, *optional*, defaults to 64): + The number of output channels for the memory encoder. + mask_downsampler_embed_dim (`int`, *optional*, defaults to 256): + The dimension of the mask downsampler embedding. + mask_downsampler_kernel_size (`int`, *optional*, defaults to 3): + The kernel size for the mask downsampler. + mask_downsampler_stride (`int`, *optional*, defaults to 2): + The stride for the mask downsampler. + mask_downsampler_padding (`int`, *optional*, defaults to 1): + The padding for the mask downsampler. + mask_downsampler_total_stride (`int`, *optional*, defaults to 16): + The total stride for the mask downsampler. + mask_downsampler_hidden_act (`str`, *optional*, defaults to `"gelu"`): + The non-linear activation function in the mask downsampler. + memory_fuser_num_layers (`int`, *optional*, defaults to 2): + The number of layers in the memory fuser. + memory_fuser_embed_dim (`int`, *optional*, defaults to 256): + The dimension of the embedding layer in the memory fuser. + memory_fuser_intermediate_dim (`int`, *optional*, defaults to 1024): + The dimension of the intermediate layer in the memory fuser. + memory_fuser_kernel_size (`int`, *optional*, defaults to 7): + The kernel size for the memory fuser. + memory_fuser_padding (`int`, *optional*, defaults to 3): + The padding for the memory fuser. + memory_fuser_layer_scale_init_value (`float`, *optional*, defaults to 1e-06): + The initial value for the layer scale in the memory fuser. + memory_fuser_hidden_act (`str`, *optional*, defaults to `"gelu"`): + The non-linear activation function in the memory fuser. + kwargs (*optional*): + Dictionary of keyword arguments. + + Example: + + ```python + >>> from transformers import ( + ... Sam3VisionConfig, + ... Sam3TrackerVideoPromptEncoderConfig, + ... Sam3TrackerVideoMaskDecoderConfig, + ... Sam3TrackerVideoModel, + ... ) + + >>> # Initializing a Sam3TrackerVideoConfig with `"facebook/sam3"` style configuration + >>> configuration = Sam3TrackerVideoConfig() + + >>> # Initializing a Sam3TrackerVideoModel (with random weights) from the `"facebook/sam3"` style configuration + >>> model = Sam3TrackerVideoModel(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + + >>> # We can also initialize a Sam3TrackerVideoConfig from a Sam3TrackerVideoVisionConfig, Sam3TrackerVideoPromptEncoderConfig, and Sam3TrackerVideoMaskDecoderConfig + + >>> # Initializing SAM3 tracker video vision encoder, memory attention, and memory encoder configurations + >>> vision_config = Sam3TrackerVideoVisionConfig() + >>> prompt_encoder_config = Sam3TrackerVideoPromptEncoderConfig() + >>> mask_decoder_config = Sam3TrackerVideoMaskDecoderConfig() + + >>> config = Sam3TrackerVideoConfig(vision_config, prompt_encoder_config, mask_decoder_config) + ```""" + + model_type = "sam3_tracker_video" + sub_configs = { + "vision_config": AutoConfig, + "prompt_encoder_config": Sam3TrackerVideoPromptEncoderConfig, + "mask_decoder_config": Sam3TrackerVideoMaskDecoderConfig, + } + + def __init__( + self, + vision_config=None, + prompt_encoder_config=None, + mask_decoder_config=None, + initializer_range=0.02, + num_maskmem=7, + image_size=1008, + sigmoid_scale_for_mem_enc=20.0, + sigmoid_bias_for_mem_enc=-10.0, + enable_occlusion_spatial_embedding=True, + multimask_output_in_sam=True, + multimask_min_pt_num=0, + multimask_max_pt_num=1, + multimask_output_for_tracking=True, + max_object_pointers_in_encoder=16, + max_cond_frame_num=4, + enable_temporal_pos_encoding_for_object_pointers=True, + # memory attention + memory_attention_hidden_size=256, + memory_attention_num_layers=4, + memory_attention_num_attention_heads=1, + memory_attention_downsample_rate=1, + memory_attention_feed_forward_hidden_size=2048, + memory_attention_feed_forward_hidden_act="relu", + memory_attention_dropout=0.1, + memory_attention_rope_theta=10000, + memory_attention_rope_feat_sizes=None, + memory_attention_rope_dropout=0.1, + # memory encoder + memory_encoder_hidden_size=256, + memory_encoder_output_channels=64, + mask_downsampler_embed_dim=256, + mask_downsampler_kernel_size=3, + mask_downsampler_stride=2, + mask_downsampler_padding=1, + mask_downsampler_total_stride=16, + mask_downsampler_hidden_act="gelu", + memory_fuser_num_layers=2, + memory_fuser_embed_dim=256, + memory_fuser_intermediate_dim=1024, + memory_fuser_kernel_size=7, + memory_fuser_padding=3, + memory_fuser_layer_scale_init_value=1e-6, + memory_fuser_hidden_act="gelu", + **kwargs, + ): + vision_config = ( + vision_config + if vision_config is not None + else {"backbone_feature_sizes": [[288, 288], [144, 144], [72, 72]]} + ) + prompt_encoder_config = prompt_encoder_config if prompt_encoder_config is not None else {} + mask_decoder_config = mask_decoder_config if mask_decoder_config is not None else {} + memory_attention_rope_feat_sizes = ( + [72, 72] if memory_attention_rope_feat_sizes is None else memory_attention_rope_feat_sizes + ) + + if isinstance(vision_config, dict): + vision_config["model_type"] = vision_config.get("model_type", "sam3_vision_model") + vision_config = CONFIG_MAPPING[vision_config["model_type"]](**vision_config) + if isinstance(prompt_encoder_config, Sam3TrackerVideoPromptEncoderConfig): + prompt_encoder_config = prompt_encoder_config.to_dict() + if isinstance(mask_decoder_config, Sam3TrackerVideoMaskDecoderConfig): + mask_decoder_config = mask_decoder_config.to_dict() + + self.vision_config = vision_config + self.prompt_encoder_config = Sam3TrackerVideoPromptEncoderConfig(**prompt_encoder_config) + self.mask_decoder_config = Sam3TrackerVideoMaskDecoderConfig(**mask_decoder_config) + + self.initializer_range = initializer_range + self.num_maskmem = num_maskmem # default 1 input frame + 6 previous frames + self.image_size = image_size + self.sigmoid_scale_for_mem_enc = sigmoid_scale_for_mem_enc + self.sigmoid_bias_for_mem_enc = sigmoid_bias_for_mem_enc + self.multimask_output_in_sam = multimask_output_in_sam + self.multimask_min_pt_num = multimask_min_pt_num + self.multimask_max_pt_num = multimask_max_pt_num + self.multimask_output_for_tracking = multimask_output_for_tracking + self.max_object_pointers_in_encoder = max_object_pointers_in_encoder + self.max_cond_frame_num = max_cond_frame_num + # The next 4 are True for sam2.1 and False for sam2 + self.enable_occlusion_spatial_embedding = enable_occlusion_spatial_embedding + self.enable_temporal_pos_encoding_for_object_pointers = enable_temporal_pos_encoding_for_object_pointers + + # memory attention + self.memory_attention_hidden_size = memory_attention_hidden_size + self.memory_attention_num_layers = memory_attention_num_layers + self.memory_attention_num_attention_heads = memory_attention_num_attention_heads + self.memory_attention_downsample_rate = memory_attention_downsample_rate + self.memory_attention_feed_forward_hidden_size = memory_attention_feed_forward_hidden_size + self.memory_attention_feed_forward_hidden_act = memory_attention_feed_forward_hidden_act + self.memory_attention_dropout = memory_attention_dropout + self.memory_attention_rope_theta = memory_attention_rope_theta + self.memory_attention_rope_feat_sizes = memory_attention_rope_feat_sizes + self.memory_attention_rope_dropout = memory_attention_rope_dropout + + # memory encoder + self.memory_encoder_hidden_size = memory_encoder_hidden_size + self.memory_encoder_output_channels = memory_encoder_output_channels + self.mask_downsampler_embed_dim = mask_downsampler_embed_dim + self.mask_downsampler_kernel_size = mask_downsampler_kernel_size + self.mask_downsampler_stride = mask_downsampler_stride + self.mask_downsampler_padding = mask_downsampler_padding + self.mask_downsampler_total_stride = mask_downsampler_total_stride + self.mask_downsampler_hidden_act = mask_downsampler_hidden_act + self.memory_fuser_num_layers = memory_fuser_num_layers + self.memory_fuser_embed_dim = memory_fuser_embed_dim + self.memory_fuser_intermediate_dim = memory_fuser_intermediate_dim + self.memory_fuser_kernel_size = memory_fuser_kernel_size + self.memory_fuser_padding = memory_fuser_padding + self.memory_fuser_layer_scale_init_value = memory_fuser_layer_scale_init_value + self.memory_fuser_hidden_act = memory_fuser_hidden_act + + super().__init__(**kwargs) + + @property + def image_size(self): + """Image size for the tracker video model.""" + return self.vision_config.image_size + + @image_size.setter + def image_size(self, value): + """Set the image size and propagate to sub-configs. Calculates feature sizes based on patch_size.""" + self.prompt_encoder_config.image_size = value + self.vision_config.image_size = value + + patch_size = self.vision_config.backbone_config.patch_size + self.vision_config.backbone_feature_sizes = [ + [4 * value // patch_size, 4 * value // patch_size], + [2 * value // patch_size, 2 * value // patch_size], + [value // patch_size, value // patch_size], + ] + self.memory_attention_rope_feat_sizes = [ + value // patch_size, + value // patch_size, + ] + + # keep the image_size in the __dict__ to save the value in the config file (backward compatibility) + self.__dict__["image_size"] = value + + +class Sam3TrackerVideoInferenceCache(Sam2VideoInferenceCache): + pass + + +class Sam3TrackerVideoInferenceSession(Sam2VideoInferenceSession): + pass + + +class Sam3TrackerVideoLayerNorm(Sam2VideoLayerNorm): + pass + + +class Sam3TrackerVideoPositionEmbeddingSine(Sam2VideoPositionEmbeddingSine): + pass + + +class Sam3TrackerVideoAttention(Sam2VideoAttention): + pass + + +class Sam3TrackerVideoTwoWayAttentionBlock(Sam2VideoTwoWayAttentionBlock): + pass + + +class Sam3TrackerVideoFeedForward(Sam2VideoFeedForward): + pass + + +class Sam3TrackerVideoImageSegmentationOutput(Sam2VideoImageSegmentationOutput): + pass + + +class Sam3TrackerVideoSegmentationOutput(Sam2VideoSegmentationOutput): + pass + + +class Sam3TrackerVideoPreTrainedModel(Sam2VideoPreTrainedModel): + pass + + +class Sam3TrackerVideoVisionRotaryEmbedding(Sam2VideoVisionRotaryEmbedding): + pass + + +class Sam3TrackerVideoRoPEAttention(Sam2VideoRoPEAttention): + pass + + +class Sam3TrackerVideoMemoryAttentionLayer(Sam2VideoMemoryAttentionLayer): + pass + + +class Sam3TrackerVideoMemoryAttention(Sam2VideoMemoryAttention): + pass + + +class Sam3TrackerVideoMemoryFuserCXBlock(Sam2VideoMemoryFuserCXBlock): + pass + + +class Sam3TrackerVideoMemoryFuser(Sam2VideoMemoryFuser): + pass + + +class Sam3TrackerVideoMaskDownSamplerLayer(Sam2VideoMaskDownSamplerLayer): + pass + + +class Sam3TrackerVideoMaskDownSampler(Sam2VideoMaskDownSampler): + pass + + +class Sam3TrackerVideoMemoryEncoder(Sam2VideoMemoryEncoder): + pass + + +class Sam3TrackerVideoVisionEncoderOutput(Sam2VideoVisionEncoderOutput): + pass + + +class Sam3TrackerVideoPositionalEmbedding(Sam2VideoPositionalEmbedding): + pass + + +class Sam3TrackerVideoMaskEmbedding(Sam2VideoMaskEmbedding): + pass + + +class Sam3TrackerVideoPromptEncoder(Sam2VideoPromptEncoder): + pass + + +class Sam3TrackerVideoTwoWayTransformer(Sam2VideoTwoWayTransformer): + pass + + +class Sam3TrackerVideoMaskDecoder(Sam2VideoMaskDecoder): + pass + + +class Sam3TrackerVideoModel(Sam2VideoModel): + _checkpoint_conversion_mapping = { + r"tracker_model.(.+)": r"\1", # the regex allows to remove the prefix, and add it back in revert mode + "detector_model.vision_encoder.backbone.": "vision_encoder.backbone.", + "tracker_neck.": "vision_encoder.neck.", + } + _keys_to_ignore_on_load_unexpected = [r"^detector_model."] + + def __init__(self, config: Sam3TrackerVideoConfig, remove_vision_encoder: bool = False): + r""" + remove_vision_encoder (`bool`, *optional*, defaults to `False`): + Whether to remove the vision encoder. If True, the vision encoder will be set to None. + """ + # loading from a sam3_video config + if hasattr(config, "tracker_config") and config.tracker_config is not None: + tracker_config = config.tracker_config + if isinstance(tracker_config, dict): + tracker_config = Sam3TrackerVideoConfig(**tracker_config) + config = tracker_config + Sam3TrackerVideoPreTrainedModel.__init__(config) + self.shared_image_embedding = Sam3TrackerVideoPositionalEmbedding(config.prompt_encoder_config) + self.vision_encoder = AutoModel.from_config(config.vision_config) if not remove_vision_encoder else None + self.prompt_encoder = Sam3TrackerVideoPromptEncoder(config.prompt_encoder_config) + # The module using it is not a PreTrainedModel subclass so we need this + config.mask_decoder_config._attn_implementation = config._attn_implementation + self.mask_decoder = Sam3TrackerVideoMaskDecoder(config.mask_decoder_config) + + self.backbone_feature_sizes = config.vision_config.backbone_feature_sizes + # a single token to indicate no memory embedding from previous frames + self.hidden_dim = config.vision_config.fpn_hidden_size + self.no_memory_embedding = torch.nn.Parameter(torch.zeros(1, 1, self.hidden_dim)) + self.config = config + # For video sequence inference + self.image_size = config.image_size + self.memory_attention = Sam3TrackerVideoMemoryAttention(config) + self.memory_encoder = Sam3TrackerVideoMemoryEncoder(config) + self.no_memory_positional_encoding = torch.nn.Parameter( + torch.zeros(1, 1, config.vision_config.fpn_hidden_size) + ) + self.mem_dim = config.memory_encoder_output_channels + self.num_maskmem = config.num_maskmem # Number of memories accessible + # Temporal encoding of the memories + self.memory_temporal_positional_encoding = torch.nn.Parameter( + torch.zeros(self.num_maskmem, 1, 1, self.mem_dim) + ) + + self.no_object_pointer = torch.nn.Parameter(torch.zeros(1, self.hidden_dim)) + # A conv layer to downsample the mask prompt to stride 4 (the same stride as + # low-res SAM mask logits) and to change its scales from 0~1 to SAM logit scale, + # so that it can be fed into the SAM mask decoder to generate a pointer. + self.mask_downsample = torch.nn.Conv2d(1, 1, kernel_size=4, stride=4) + # a feedforward layer on SAM output tokens to turn them into object pointers + self.object_pointer_proj = Sam3TrackerVideoFeedForward(self.hidden_dim, self.hidden_dim, self.hidden_dim, 3) + + if self.config.enable_temporal_pos_encoding_for_object_pointers: + # a linear projection on temporal positional encoding in object pointers to + # avoid potential interference with spatial positional encoding + self.temporal_positional_encoding_projection_layer = torch.nn.Linear(self.hidden_dim, self.mem_dim) + else: + self.temporal_positional_encoding_projection_layer = torch.nn.Identity() + + self.occlusion_spatial_embedding_parameter = None # compatibility with Sam2 + if config.enable_occlusion_spatial_embedding: + self.occlusion_spatial_embedding_parameter = torch.nn.Parameter(torch.zeros(1, self.mem_dim)) + + self.post_init() + + @can_return_tuple + @auto_docstring + def get_image_features( + self, + pixel_values: torch.FloatTensor, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple | Sam3TrackerVideoVisionEncoderOutput: + r""" + pixel_values (`torch.FloatTensor`): + Input pixel values of shape `(batch_size, num_channels, height, width)`. + """ + vision_outputs: Sam3TrackerVideoVisionEncoderOutput = self.vision_encoder( + pixel_values, return_dict=True, **kwargs + ) + + feature_maps = vision_outputs.fpn_hidden_states + feature_maps_position_embeddings = vision_outputs.fpn_position_encoding + + # precompute projected level 0 and level 1 features in SAM decoder + # to avoid running it again on every SAM click + feature_maps = list(feature_maps[:-1]) + feature_maps[0] = self.mask_decoder.conv_s0(feature_maps[0]) + feature_maps[1] = self.mask_decoder.conv_s1(feature_maps[1]) + + # flatten NxCxHxW to HWxNxC + feature_maps = [feature_map.flatten(2).permute(2, 0, 1) for feature_map in feature_maps] + feature_maps_position_embeddings = [ + feature_map_position_embedding.flatten(2).permute(2, 0, 1) + for feature_map_position_embedding in feature_maps_position_embeddings[:-1] + ] + vision_outputs.fpn_hidden_states = feature_maps + vision_outputs.fpn_position_encoding = feature_maps_position_embeddings + + return vision_outputs + + +__all__ = [ + "Sam3TrackerVideoMaskDecoderConfig", + "Sam3TrackerVideoPromptEncoderConfig", + "Sam3TrackerVideoConfig", + "Sam3TrackerVideoModel", + "Sam3TrackerVideoInferenceSession", + "Sam3TrackerVideoPreTrainedModel", + "Sam3TrackerVideoProcessor", +] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam3_tracker_video/processing_sam3_tracker_video.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam3_tracker_video/processing_sam3_tracker_video.py new file mode 100644 index 0000000000000000000000000000000000000000..708be51bd5e32fb25297c130c8d5c26fb289d768 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam3_tracker_video/processing_sam3_tracker_video.py @@ -0,0 +1,803 @@ +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# This file was automatically generated from src/transformers/models/sam3_tracker_video/modular_sam3_tracker_video.py. +# Do NOT edit this file manually as any edits will be overwritten by the generation of +# the file from the modular. If any change should be done, please apply the change to the +# modular_sam3_tracker_video.py file directly. One of our CI enforces this. +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# Copyright 2025 the HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + + +from copy import deepcopy +from typing import Union + +import numpy as np +import torch + +from ...image_utils import ImageInput +from ...processing_utils import ProcessorMixin +from ...tokenization_utils_base import BatchEncoding +from ...utils import TensorType, auto_docstring +from ...utils.import_utils import requires +from ...video_utils import VideoInput +from .modeling_sam3_tracker_video import Sam3TrackerVideoInferenceSession + + +@requires(backends=("torch",)) +@auto_docstring +class Sam3TrackerVideoProcessor(ProcessorMixin): + def __init__( + self, image_processor, video_processor, target_size: int | None = None, point_pad_value: int = -10, **kwargs + ): + r""" + target_size (`int`, *optional*): + The target size (in pixels) for normalizing input points and bounding boxes. If not provided, defaults + to the image processor's size configuration. All input coordinates (points and boxes) are normalized + to this size before being passed to the model. This ensures consistent coordinate representation + regardless of the original image dimensions. + point_pad_value (`int`, *optional*, defaults to -10): + The value used for padding input points when batching sequences of different lengths. This value is + used to mark padded positions and is preserved during coordinate normalization. + """ + super().__init__(image_processor, video_processor, **kwargs) + self.point_pad_value = point_pad_value + self.target_size = target_size if target_size is not None else self.image_processor.size["height"] + + @auto_docstring + def __call__( + self, + images: ImageInput | None = None, + segmentation_maps: ImageInput | None = None, + input_points: list[list[list[list[float]]]] | torch.Tensor | None = None, + input_labels: list[list[list[int]]] | torch.Tensor | None = None, + input_boxes: list[list[list[float]]] | torch.Tensor | None = None, + original_sizes: list[list[float]] | torch.Tensor | None = None, + return_tensors: str | TensorType | None = None, + **kwargs, + ) -> BatchEncoding: + r""" + segmentation_maps (`ImageInput`, *optional*): + The segmentation maps to process. + input_points (`list[list[list[list[float]]]]`, `torch.Tensor`, *optional*): + The points to add to the frame. + input_labels (`list[list[list[int]]]`, `torch.Tensor`, *optional*): + The labels for the points. + input_boxes (`list[list[list[float]]]`, `torch.Tensor`, *optional*): + The bounding boxes to add to the frame. + original_sizes (`list[list[float]]`, `torch.Tensor`, *optional*): + The original sizes of the images. + + Returns: + A [`BatchEncoding`] with the following fields: + - `pixel_values` (`torch.Tensor`): The processed image(s). + - `original_sizes` (`list[list[float]]`): The original sizes of the images. + - `labels` (`torch.Tensor`): The processed segmentation maps (if provided). + - `input_points` (`torch.Tensor`): The processed points. + - `input_labels` (`torch.Tensor`): The processed labels. + - `input_boxes` (`torch.Tensor`): The processed bounding boxes. + """ + if images is not None: + encoding_image_processor = self.image_processor( + images, + segmentation_maps=segmentation_maps, + return_tensors=return_tensors, + **kwargs, + ) + elif original_sizes is not None: + if isinstance(original_sizes, torch.Tensor): + original_sizes = original_sizes.cpu().tolist() + encoding_image_processor = BatchEncoding({"original_sizes": original_sizes}, tensor_type=return_tensors) + else: + raise ValueError("Either images or original_sizes must be provided") + + # pop arguments that are not used in the forward but used nevertheless + original_sizes = encoding_image_processor["original_sizes"] + # Check original_sizes is of length 1 or len(images) + if images is not None and len(original_sizes) != 1 and len(original_sizes) != len(images): + raise ValueError( + "original_sizes must be of length 1 or len(images). If you are passing a single image, you must pass a single original_size." + ) + + # Process input points, labels, and boxes if provided + if input_points is not None or input_labels is not None or input_boxes is not None: + # Validate and convert inputs to standardized format + processed_points = self._validate_single_input( + input_points, + expected_depth=4, + input_name="points", + expected_format="[image level, object level, point level, point coordinates]", + expected_coord_size=2, + ) + processed_labels = self._validate_single_input( + input_labels, + expected_depth=3, + input_name="labels", + expected_format="[image level, object level, point level]", + ) + processed_boxes = self._validate_single_input( + input_boxes, + expected_depth=3, + input_name="boxes", + expected_format="[image level, box level, box coordinates]", + expected_coord_size=4, + ) + + # Get padding requirements for all inputs + if processed_points is not None: + points_max_dims = self._get_nested_dimensions(processed_points)[:3] + if processed_labels is not None: + labels_max_dims = self._get_nested_dimensions(processed_labels)[:3] + if processed_boxes is not None: + boxes_max_dims = self._get_nested_dimensions(processed_boxes)[:2] + + # Ensure points and labels have consistent dimensions + if processed_points is not None and processed_labels is not None: + if points_max_dims != labels_max_dims: + raise ValueError( + "Input points and labels have inconsistent dimensions. Please ensure they have the same dimensions." + ) + + # Check that boxes don't need padding (model limitation) + if processed_boxes is not None and len(processed_boxes) >= 2: + if any(len(img_boxes) < boxes_max_dims[1] for img_boxes in processed_boxes): + raise ValueError( + "Input boxes have inconsistent dimensions that would require padding, " + "but boxes cannot be padded due to model limitations. " + "Please ensure all images have the same number of boxes." + ) + + # Pad and normalize all inputs to final tensor format + if processed_points is not None: + padded_points = self._pad_nested_list(processed_points, points_max_dims + [2]) + final_points = torch.tensor(padded_points, dtype=torch.float32) + self._normalize_tensor_coordinates(final_points, original_sizes, preserve_padding=True) + encoding_image_processor.update({"input_points": final_points}) + + if processed_labels is not None: + padded_labels = self._pad_nested_list(processed_labels, labels_max_dims) + final_labels = torch.tensor(padded_labels, dtype=torch.int64) + encoding_image_processor.update({"input_labels": final_labels}) + + if processed_boxes is not None: + final_boxes = torch.tensor(processed_boxes, dtype=torch.float32) + self._normalize_tensor_coordinates(final_boxes, original_sizes, is_bounding_box=True) + encoding_image_processor.update({"input_boxes": final_boxes}) + + return encoding_image_processor + + def _normalize_coordinates( + self, target_size: int, coords: "torch.Tensor", original_size, is_bounding_box=False + ) -> "torch.Tensor": + """ + Expects a numpy array of length 2 in the final dimension. Requires the original image size in (H, W) format. + + Args: + target_size (`int`): + The target size of the image. + coords (`torch.Tensor`): + The coordinates to be normalized. + original_size (`tuple`): + The original size of the image. + is_bounding_box (`bool`, *optional*, defaults to `False`): + Whether the coordinates are bounding boxes. + """ + old_h, old_w = original_size + new_h, new_w = target_size, target_size + coords = deepcopy(coords).float() + + if is_bounding_box: + coords = coords.reshape(-1, 2, 2) + coords[..., 0] = coords[..., 0] * (new_w / old_w) + coords[..., 1] = coords[..., 1] * (new_h / old_h) + + if is_bounding_box: + coords = coords.reshape(-1, 4) + + return coords + + def _convert_to_nested_list(self, data, expected_depth, current_depth=0): + """ + Recursively convert various input formats (tensors, numpy arrays, lists) to nested lists. + + Args: + data: Input data in any format + expected_depth: Expected nesting depth + current_depth: Current depth in recursion + + Returns: + Nested list representation of the data + """ + if data is None: + return None + + # Convert tensor/numpy to list if we're at a leaf level or if it's a multi-dimensional array + if isinstance(data, torch.Tensor): # PyTorch tensor + if current_depth == expected_depth - 2 or len(data.shape) <= 2: # At coordinate level or small tensor + return data.numpy().tolist() + else: + return [self._convert_to_nested_list(item, expected_depth, current_depth + 1) for item in data] + elif isinstance(data, np.ndarray): # NumPy array + if current_depth == expected_depth - 2 or len(data.shape) <= 2: # At coordinate level or small array + return data.tolist() + else: + return [self._convert_to_nested_list(item, expected_depth, current_depth + 1) for item in data] + elif isinstance(data, list): + if current_depth == expected_depth: + # We've reached the expected depth, return as is + return data + else: + # Continue recursion + return [self._convert_to_nested_list(item, expected_depth, current_depth + 1) for item in data] + elif isinstance(data, (int, float)): + return data + else: + raise TypeError(f"Unsupported data type: {type(data)}") + + def _get_nested_dimensions(self, nested_list, max_dims=None): + """ + Get the maximum dimensions at each level of nesting. + + Args: + nested_list (`list`): + Nested list structure. + max_dims (`list`, *optional*): + Current maximum dimensions (for recursion). + + Returns: + `list`: A list of maximum dimensions for each nesting level. + """ + if max_dims is None: + max_dims = [] + + if not isinstance(nested_list, list): + return max_dims + + if len(max_dims) == 0: + max_dims.append(len(nested_list)) + else: + max_dims[0] = max(max_dims[0], len(nested_list)) + + if len(nested_list) > 0: + for item in nested_list: + if isinstance(item, list): + sub_dims = self._get_nested_dimensions(item) + # Merge sub_dims into max_dims + for i, dim in enumerate(sub_dims): + if i + 1 >= len(max_dims): + max_dims.append(dim) + else: + max_dims[i + 1] = max(max_dims[i + 1], dim) + + return max_dims + + def _pad_nested_list(self, nested_list, target_dims, current_level=0, pad_value=None): + """ + Recursively pad a nested list to match target dimensions. + + Args: + nested_list (`list`): + Nested list to pad. + target_dims (`list`): + Target dimensions for each level. + current_level (`int`, *optional*, defaults to 0): + Current nesting level. + pad_value (`int`, *optional*): + Value to use for padding. + + Returns: + `list`: The padded nested list. + """ + if pad_value is None: + pad_value = self.point_pad_value + + if current_level >= len(target_dims): + return nested_list + + # Ensure we have a list + if not isinstance(nested_list, list): + nested_list = [nested_list] + + # Pad current level + current_size = len(nested_list) + target_size = target_dims[current_level] + + # Pad with appropriate values + if current_level == len(target_dims) - 1: + # At the coordinate level, pad with pad_value + nested_list.extend([pad_value] * (target_size - current_size)) + else: + # At higher levels, pad with nested structures + if current_size > 0: + # Create appropriately sized template + if current_level < len(target_dims) - 2: + # For non-coordinate levels, create empty nested structure + template_dims = target_dims[current_level + 1 :] + template = self._create_empty_nested_structure(template_dims, pad_value) + else: + # For coordinate level, create list of pad_values + template = [pad_value] * target_dims[current_level + 1] + + nested_list.extend([deepcopy(template) for _ in range(target_size - current_size)]) + else: + # Create from scratch + template_dims = target_dims[current_level + 1 :] + template = self._create_empty_nested_structure(template_dims, pad_value) + nested_list.extend([deepcopy(template) for _ in range(target_size)]) + + # Recursively pad sublists + if current_level < len(target_dims) - 1: + for i in range(len(nested_list)): + if isinstance(nested_list[i], list): + nested_list[i] = self._pad_nested_list(nested_list[i], target_dims, current_level + 1, pad_value) + + return nested_list + + def _create_empty_nested_structure(self, dims, pad_value): + """ + Create an empty nested structure with given dimensions filled with pad_value. + + Args: + dims (`list`): + The dimensions of the nested structure. + pad_value (`int`): + The value to fill the structure with. + """ + if len(dims) == 1: + return [pad_value] * dims[0] + else: + return [self._create_empty_nested_structure(dims[1:], pad_value) for _ in range(dims[0])] + + def _get_nesting_level(self, input_list): + """ + Get the nesting level of a list structure. + + Args: + input_list (`list`): + The list to get the nesting level of. + """ + if isinstance(input_list, list): + if len(input_list) == 0: + return 1 + return 1 + self._get_nesting_level(input_list[0]) + elif isinstance(input_list, (np.ndarray, torch.Tensor)): + # For arrays/tensors, the nesting level is the number of dimensions + return len(input_list.shape) + return 0 + + def _validate_single_input( + self, + data: torch.Tensor | np.ndarray | list, + expected_depth: int, + input_name: str, + expected_format: str, + expected_coord_size: int | None = None, + ) -> list: + """ + Validate a single input by ensuring proper nesting and raising an error if the input is not valid. + + Args: + data (`torch.Tensor`, `np.ndarray`, or `list`): + Input data to process. + expected_depth (`int`): + Expected nesting depth. + input_name (`str`): + Name of the input for error messages. + expected_format (`str`): + The expected format of the input. + expected_coord_size (`int`, *optional*): + Expected coordinate size (2 for points, 4 for boxes, None for labels). + . + """ + if data is None: + return None + + # Handle tensors and numpy arrays first + if isinstance(data, (torch.Tensor, np.ndarray)): + # For tensors/arrays, we can directly check the number of dimensions + if data.ndim != expected_depth: + raise ValueError( + f"Input {input_name} must be a tensor/array with {expected_depth} dimensions. The expected nesting format is {expected_format}. Got {data.ndim} dimensions." + ) + elif expected_coord_size is not None: + if data.shape[-1] != expected_coord_size: + raise ValueError( + f"Input {input_name} must be a tensor/array with {expected_coord_size} as the last dimension, got {data.shape[-1]}." + ) + return self._convert_to_nested_list(data, expected_depth) + + # Handle nested lists + if isinstance(data, list): + current_depth = self._get_nesting_level(data) + if current_depth != expected_depth: + raise ValueError( + f"Input {input_name} must be a nested list with {expected_depth} levels. The expected nesting format is {expected_format}. Got {current_depth} levels." + ) + return self._convert_to_nested_list(data, expected_depth) + + def _normalize_tensor_coordinates(self, tensor, original_sizes, is_bounding_box=False, preserve_padding=False): + """ + Helper method to normalize coordinates in a tensor across multiple images. + + Args: + tensor (`torch.Tensor`): + Input tensor with coordinates. + original_sizes (`list`): + Original image sizes. + is_bounding_box (`bool`, *optional*, defaults to `False`): + Whether coordinates are bounding boxes. + preserve_padding (`bool`, *optional*, defaults to `False`): + Whether to preserve padding values (for points). + """ + if preserve_padding: + # For points: avoid normalizing pad values + mask = tensor != self.point_pad_value + coord_mask = mask.all(dim=-1, keepdim=True) + + for img_idx in range(len(original_sizes)): + if img_idx < tensor.shape[0]: + original_size = original_sizes[img_idx] if img_idx < len(original_sizes) else original_sizes[0] + normalized_coords = self._normalize_coordinates( + self.target_size, tensor[img_idx], original_size, is_bounding_box=is_bounding_box + ) + + if preserve_padding: + # Only update non-padded values + img_mask = coord_mask[img_idx] + tensor[img_idx] = torch.where( + img_mask.expand_as(tensor[img_idx]), normalized_coords, tensor[img_idx] + ) + else: + tensor[img_idx] = normalized_coords + + def post_process_masks( + self, + masks, + original_sizes, + mask_threshold=0.0, + binarize=True, + max_hole_area=0.0, + max_sprinkle_area=0.0, + apply_non_overlapping_constraints=False, + **kwargs, + ): + """ + Remove padding and upscale masks to the original image size. + + Args: + masks (`Union[List[torch.Tensor], List[np.ndarray]]`): + Batched masks from the mask_decoder in (batch_size, num_channels, height, width) format. + original_sizes (`Union[torch.Tensor, List[Tuple[int,int]]]`): + The original sizes of each image before it was resized to the model's expected input shape, in (height, + width) format. + mask_threshold (`float`, *optional*, defaults to 0.0): + Threshold for binarization and post-processing operations. + binarize (`bool`, *optional*, defaults to `True`): + Whether to binarize the masks. + max_hole_area (`float`, *optional*, defaults to 0.0): + The maximum area of a hole to fill. + max_sprinkle_area (`float`, *optional*, defaults to 0.0): + The maximum area of a sprinkle to fill. + apply_non_overlapping_constraints (`bool`, *optional*, defaults to `False`): + Whether to apply non-overlapping constraints to the masks. + + Returns: + (`torch.Tensor`): Batched masks in batch_size, num_channels, height, width) format, where (height, width) + is given by original_size. + """ + return self.image_processor.post_process_masks( + masks, + original_sizes, + mask_threshold, + binarize, + max_hole_area, + max_sprinkle_area, + apply_non_overlapping_constraints, + **kwargs, + ) + + @property + def model_input_names(self): + image_processor_input_names = self.image_processor.model_input_names + return list(image_processor_input_names + ["original_sizes"]) + + def init_video_session( + self, + video: VideoInput | None = None, + inference_device: Union[str, "torch.device"] = "cpu", + inference_state_device: Union[str, "torch.device"] | None = None, + processing_device: Union[str, "torch.device"] | None = None, + video_storage_device: Union[str, "torch.device"] | None = None, + max_vision_features_cache_size: int = 1, + dtype: torch.dtype = torch.float32, + ): + """ + Initializes a video session for inference. + If a video is provided (async inference), the video will be processed and stored on the `video_storage_device`. + + Args: + video (`VideoInput`, *optional*): + The video to process. No need to provide when streaming. + inference_device (`str` or `torch.device`, *optional*, defaults to "cpu"): + The device to use for inference. + inference_state_device (`str` or `torch.device`, *optional*): + The device to store the inference state on. + processing_device (`str` or `torch.device`, *optional*): + The device to use for video processing. + video_storage_device (`str` or `torch.device`, *optional*): + The device to store the processed video frames on. + max_vision_features_cache_size (`int`, *optional*, defaults to 1): + The maximum number of vision features to cache. + dtype (`torch.dtype`, *optional*, defaults to `torch.float32`): + The torch dtype to use for the whole session. + """ + video_storage_device = video_storage_device if video_storage_device is not None else inference_device + inference_state_device = inference_state_device if inference_state_device is not None else inference_device + processing_device = processing_device if processing_device is not None else inference_device + pixel_values_video = None + video_height = None + video_width = None + if video is not None: + processed_video = self.video_processor(videos=video, device=processing_device, return_tensors="pt") + pixel_values_video = processed_video.pixel_values_videos[0] + video_height = processed_video.original_sizes[0][0] + video_width = processed_video.original_sizes[0][1] + inference_session = Sam3TrackerVideoInferenceSession( + video=pixel_values_video, + video_height=video_height, + video_width=video_width, + inference_device=inference_device, + video_storage_device=video_storage_device, + inference_state_device=inference_state_device, + dtype=dtype, + max_vision_features_cache_size=max_vision_features_cache_size, + ) + return inference_session + + def add_inputs_to_inference_session( + self, + inference_session: Sam3TrackerVideoInferenceSession, + frame_idx: int, + obj_ids: list[int] | int, + input_points: list[list[list[list[float]]]] | torch.Tensor | None = None, + input_labels: list[list[list[int]]] | torch.Tensor | None = None, + input_boxes: list[list[list[float]]] | torch.Tensor | None = None, + input_masks: np.ndarray | torch.Tensor | list[np.ndarray] | list[torch.Tensor] | None = None, + original_size: tuple[int, int] | None = None, + clear_old_inputs: bool = True, + ) -> Sam3TrackerVideoInferenceSession: + """ + Process new points, boxes, or masks for a video frame and add them to the inference session. + + Args: + inference_session (`Sam3TrackerVideoInferenceSession`): + The inference session for the video. + frame_idx (`int`): + The index of the frame to process. + obj_ids (`list[int]` or `int`): + The object ID(s) to associate with the points or box. + These can be any integers and can be reused later on to specify an object. + input_points (`list[list[list[list[float]]]]`, `torch.Tensor`, *optional*): + The points to add to the frame. + input_labels (`list[list[list[int]]]`, `torch.Tensor`, *optional*): + The labels for the points. + input_boxes (`list[list[list[float]]]`, `torch.Tensor`, *optional*): + The bounding boxes to add to the frame. + input_masks (`np.ndarray`, `torch.Tensor`, `list[np.ndarray]`, or `list[torch.Tensor]`, *optional*): + The mask(s) to add to the frame. + original_size (`tuple[int, int]`, *optional*): + The original size of the video. Provide when streaming. + clear_old_inputs (`bool`, *optional*, defaults to `True`): + Whether to clear old inputs for the object. + """ + + if isinstance(obj_ids, int): + obj_ids = [obj_ids] + + # Validate inputs + if (input_points is not None) != (input_labels is not None): + raise ValueError("points and labels must be provided together") + if input_points is None and input_boxes is None and input_masks is None: + raise ValueError("at least one of points, boxes, or masks must be provided as input") + if input_masks is not None and (input_points is not None or input_boxes is not None): + raise ValueError("masks cannot be provided together with points or boxes") + + if input_masks is not None: + return self.process_new_mask_for_video_frame(inference_session, frame_idx, obj_ids, input_masks) + else: + return self.process_new_points_or_boxes_for_video_frame( + inference_session, + frame_idx, + obj_ids, + input_points, + input_labels, + input_boxes, + original_size, + clear_old_inputs, + ) + + def process_new_points_or_boxes_for_video_frame( + self, + inference_session: Sam3TrackerVideoInferenceSession, + frame_idx: int, + obj_ids: list[int], + input_points: list[list[list[list[float]]]] | torch.Tensor | None = None, + input_labels: list[list[list[int]]] | torch.Tensor | None = None, + input_boxes: list[list[list[float]]] | torch.Tensor | None = None, + original_size: tuple[int, int] | None = None, + clear_old_inputs: bool = True, + ) -> Sam3TrackerVideoInferenceSession: + """ + Process new points or boxes for a video frame and add them to the inference session. + + Args: + inference_session (`Sam3TrackerVideoInferenceSession`): + The inference session for the video. + frame_idx (`int`): + The index of the frame to process. + obj_ids (`list[int]`): + The object ID(s) to associate with the points or box. + These can be any integers and can be reused later on to specify an object. + input_points (`list[list[list[list[float]]]]`, `torch.Tensor`, *optional*): + The points to add to the frame. + input_labels (`list[list[list[int]]]`, `torch.Tensor`, *optional*): + The labels for the points. + input_boxes (`list[list[list[float]]]`, `torch.Tensor`, *optional*): + The bounding boxes to add to the frame. + original_size (`tuple[int, int]`, *optional*): + The original size of the video. Provide when streaming. + clear_old_inputs (`bool`, *optional*, defaults to `True`): + Whether to clear old inputs for the object. + """ + if original_size is not None: + inference_session.video_height = original_size[0] + inference_session.video_width = original_size[1] + elif inference_session.video_height is None or inference_session.video_width is None: + raise ValueError("original_size must be provided when adding points or boxes on a first streamed frame") + + original_sizes = [[inference_session.video_height, inference_session.video_width]] + + encoded_inputs = self( + input_points=input_points, + input_labels=input_labels, + input_boxes=input_boxes, + original_sizes=original_sizes, + return_tensors="pt", + ) + input_points = encoded_inputs.get("input_points", None) + input_labels = encoded_inputs.get("input_labels", None) + input_boxes = encoded_inputs.get("input_boxes", None) + + if input_points is not None: + if input_points.shape[1] != len(obj_ids): + raise ValueError( + f"Number of object ids ({len(obj_ids)}) does not match number of points ({input_points.shape[1]})" + ) + else: + input_points = torch.zeros(1, len(obj_ids), 0, 2, dtype=torch.float32) + if input_labels is not None: + if input_labels.shape[1] != len(obj_ids): + raise ValueError( + f"Number of object ids ({len(obj_ids)}) does not match number of labels ({input_labels.shape[1]})" + ) + else: + input_labels = torch.zeros(1, len(obj_ids), 0, dtype=torch.int32) + if input_boxes is not None: + if input_boxes.shape[1] != len(obj_ids): + raise ValueError( + f"Number of object ids ({len(obj_ids)}) does not match number of boxes ({input_boxes.shape[1]})" + ) + + if input_boxes is not None: + if not clear_old_inputs: + raise ValueError( + "cannot add box without clearing old points, since " + "box prompt must be provided before any point prompt " + "(please use clear_old_points=True instead)" + ) + box_coords = input_boxes.reshape(1, -1, 2, 2) + box_labels = torch.tensor([2, 3], dtype=torch.int32).repeat(1, box_coords.shape[1], 1) + input_points = torch.cat([box_coords, input_points], dim=2) + input_labels = torch.cat([box_labels, input_labels], dim=2) + + for obj_id, idx in zip(obj_ids, range(len(obj_ids))): + obj_idx = inference_session.obj_id_to_idx(obj_id) + input_points_for_obj = input_points[:, idx, :, :].unsqueeze(1) + input_labels_for_obj = input_labels[:, idx, :].unsqueeze(1) + # Handle existing points + if not clear_old_inputs: + existing_points = inference_session.point_inputs_per_obj[obj_idx].get(frame_idx, None) + if existing_points is not None: + # Concatenate with existing points + input_points_for_obj = torch.cat( + [existing_points["point_coords"].to(input_points_for_obj.device), input_points_for_obj], dim=2 + ) + input_labels_for_obj = torch.cat( + [existing_points["point_labels"].to(input_labels_for_obj.device), input_labels_for_obj], dim=2 + ) + point_inputs = { + "point_coords": input_points_for_obj, + "point_labels": input_labels_for_obj, + } + + inference_session.add_point_inputs(obj_idx, frame_idx, point_inputs) + inference_session.remove_mask_inputs(obj_idx, frame_idx) # Clear any mask inputs + + inference_session.obj_with_new_inputs = obj_ids + + def process_new_mask_for_video_frame( + self, + inference_session: Sam3TrackerVideoInferenceSession, + frame_idx: int, + obj_ids: list[int], + input_masks: np.ndarray | torch.Tensor | list[np.ndarray] | list[torch.Tensor], + ): + """ + Add new mask to a frame and add them to the inference session. + + Args: + inference_session (`Sam3TrackerVideoInferenceSession`): + The inference session for the video. + frame_idx (`int`): + The index of the frame to process. + obj_ids (`list[int]`): + The object ID(s) to associate with the mask. + These can be any integers and can be reused later on to specify an object. + input_masks (`np.ndarray`, `torch.Tensor`, `list[np.ndarray]`, or `list[torch.Tensor]`): + The mask(s) to add to the frame. + """ + if not isinstance(input_masks, list): + input_masks = [input_masks] + if len(input_masks) != len(obj_ids): + raise ValueError( + f"Number of object ids ({len(obj_ids)}) does not match number of masks ({len(input_masks)})" + ) + + for obj_id, mask in zip(obj_ids, input_masks): + obj_idx = inference_session.obj_id_to_idx(obj_id) + + device = inference_session.inference_device + + # Process mask + if not isinstance(mask, torch.Tensor): + mask = torch.tensor(mask, dtype=torch.bool) + nb_dim = mask.dim() + if nb_dim > 4 or nb_dim < 2: + raise ValueError(f"Mask has an unsupported number of dimensions: {nb_dim}") + for i in range(4 - nb_dim): + mask = mask.unsqueeze(0) + + mask_H, mask_W = mask.shape[-2:] + mask_inputs_orig = mask.to(device) + mask_inputs_orig = mask_inputs_orig.float().to(device) + + # Resize mask if needed + if mask_H != self.target_size or mask_W != self.target_size: + mask_inputs = torch.nn.functional.interpolate( + mask_inputs_orig, + size=(self.target_size, self.target_size), + align_corners=False, + mode="bilinear", + antialias=True, + ) + mask_inputs = (mask_inputs >= 0.5).float() + else: + mask_inputs = mask_inputs_orig + + inference_session.add_mask_inputs(obj_idx, frame_idx, mask_inputs) + inference_session.remove_point_inputs(obj_idx, frame_idx) # Clear any point inputs + + inference_session.obj_with_new_inputs = obj_ids + + +__all__ = ["Sam3TrackerVideoProcessor"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam3_video/__init__.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam3_video/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..97943d102b6ed94e328e4ff49162894fec0a38f5 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam3_video/__init__.py @@ -0,0 +1,28 @@ +# Copyright 2025 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from typing import TYPE_CHECKING + +from ...utils import _LazyModule +from ...utils.import_utils import define_import_structure + + +if TYPE_CHECKING: + from .configuration_sam3_video import * + from .modeling_sam3_video import * + from .processing_sam3_video import * +else: + import sys + + _file = globals()["__file__"] + sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__) diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam3_video/configuration_sam3_video.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam3_video/configuration_sam3_video.py new file mode 100644 index 0000000000000000000000000000000000000000..175f003a63095845af1f4fc4183ad053cf5c0a4a --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam3_video/configuration_sam3_video.py @@ -0,0 +1,242 @@ +# Copyright 2025 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""SAM3 Video model configuration""" + +from ...configuration_utils import PreTrainedConfig +from ...utils import logging +from ..auto import CONFIG_MAPPING, AutoConfig + + +logger = logging.get_logger(__name__) + + +class Sam3VideoConfig(PreTrainedConfig): + r""" + Configuration class for [`Sam3VideoModel`]. This combines configurations for the detector (Sam3) and tracker + (Sam2Video) components, along with detection-tracking fusion hyperparameters. + + Instantiating a configuration defaults will yield a similar configuration to that of SAM 3 + [facebook/sam3](https://huggingface.co/facebook/sam3) architecture. + + This model integrates detection and tracking with various fusion heuristics including NMS, association, + hotstart, reconditioning, and occlusion handling. + + Args: + detector_config (`dict` or `Sam3Config`, *optional*): + Configuration for the Sam3 detector model. If not provided, default Sam3Config will be used. + tracker_config (`dict` or `Sam2VideoConfig`, *optional*): + Configuration for the Sam2Video tracker model. If not provided, default Sam2VideoConfig will be used. + initializer_range (`float`, *optional*, defaults to 0.02): + The standard deviation of the truncated_normal_initializer for initializing weight matrices. + low_res_mask_size (`int`, *optional*, defaults to 288): + Size (height and width) of the low-resolution mask outputs from the tracker before upsampling to video resolution. + score_threshold_detection (`float`, *optional*, defaults to 0.5): + Probability threshold for detection outputs - only keep detections above this threshold. + det_nms_thresh (`float`, *optional*, defaults to 0.1): + IoU threshold for detection NMS (Non-Maximum Suppression). + assoc_iou_thresh (`float`, *optional*, defaults to 0.1): + IoU threshold for detection-to-track matching. A detection is considered "matched" to a tracklet if + it overlaps with the tracklet above this threshold. Often a loose threshold like 0.1. + trk_assoc_iou_thresh (`float`, *optional*, defaults to 0.5): + IoU threshold for detection-to-track matching, used to determine whether a masklet is "unmatched" + by any detections. Often a stricter threshold like 0.5. + new_det_thresh (`float`, *optional*, defaults to 0.7): + Probability threshold for a detection to be added as a new object. + recondition_on_trk_masks (`bool`, *optional*, defaults to `True`): + Whether to use tracked masks (True) or detection masks (False) for reconditioning. Use True when tracked + masks are higher quality and detector serves as validation signal to strengthen memory and prevent drift. + hotstart_delay (`int`, *optional*, defaults to 15): + Number of frames to buffer outputs during hotstart. We hold off the outputs for `hotstart_delay` + frames and remove tracklets based on hotstart heuristics. + hotstart_unmatch_thresh (`int`, *optional*, defaults to 8): + Number of unmatched frames required to remove a tracklet during hotstart period. + hotstart_dup_thresh (`int`, *optional*, defaults to 8): + Number of overlapping frames required to remove a duplicate tracklet during hotstart period. + suppress_unmatched_only_within_hotstart (`bool`, *optional*, defaults to `True`): + Whether to suppress masks only within hotstart period. If False, we can suppress masks even if + they start before hotstart period. + init_trk_keep_alive (`int`, *optional*, defaults to 30): + Initial keep-alive counter for new tracks. + max_trk_keep_alive (`int`, *optional*, defaults to 30): + Maximum keep-alive counter value. Tracks with matched detections get their counter increased up to this value. + min_trk_keep_alive (`int`, *optional*, defaults to -1): + Minimum keep-alive counter value. Tracks with unmatched detections get their counter decreased to this value. + suppress_overlapping_based_on_recent_occlusion_threshold (`float`, *optional*, defaults to 0.7): + Threshold for suppressing overlapping objects based on recent occlusion. Overlapping masks with + IoU above this threshold are suppressed based on which was most recently occluded. + decrease_trk_keep_alive_for_empty_masklets (`bool`, *optional*, defaults to `False`): + Whether to decrease keep-alive counter for masklets with zero area in SAM2 prediction. + fill_hole_area (`int`, *optional*, defaults to 16): + Minimum area (in pixels) for filling holes in masks and removing small sprinkles. + max_num_objects (`int`, *optional*, defaults to 10000): + Maximum number of objects to track. Default 10000 effectively turns off this limit. + recondition_every_nth_frame (`int`, *optional*, defaults to 16): + Frequency of mask reconditioning (in frames). Set to 0 to disable reconditioning. + high_conf_thresh (`float`, *optional*, defaults to 0.8): + High confidence threshold for reconditioning. Only detections above this threshold can recondition tracklets. + high_iou_thresh (`float`, *optional*, defaults to 0.8): + High IoU threshold for reconditioning. Only detections with IoU above this threshold can recondition tracklets. + + Example: + ```python + >>> from transformers import Sam3VideoConfig, Sam3VideoModel + + >>> # Initializing a SAM3 Video configuration with default detector and tracker + >>> configuration = Sam3VideoConfig() + + >>> # Changing image size for custom resolution inference (automatically propagates to all nested configs) + >>> configuration.image_size = 560 + + >>> # Initializing a model from the configuration + >>> model = Sam3VideoModel(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + >>> detector_config = configuration.detector_config + >>> tracker_config = configuration.tracker_config + ``` + """ + + model_type = "sam3_video" + is_composition = True + sub_configs = { + "detector_config": AutoConfig, + "tracker_config": AutoConfig, + } + + def __init__( + self, + detector_config=None, + tracker_config=None, + initializer_range=0.02, + low_res_mask_size=288, + # Detection-tracking fusion hyperparameters + score_threshold_detection=0.5, + det_nms_thresh=0.1, + assoc_iou_thresh=0.1, + trk_assoc_iou_thresh=0.5, + new_det_thresh=0.7, + recondition_on_trk_masks=True, + # Hotstart parameters + hotstart_delay=15, + hotstart_unmatch_thresh=8, + hotstart_dup_thresh=8, + suppress_unmatched_only_within_hotstart=True, + # Keep-alive parameters + init_trk_keep_alive=30, + max_trk_keep_alive=30, + min_trk_keep_alive=-1, + # Occlusion and overlap handling + suppress_overlapping_based_on_recent_occlusion_threshold=0.7, + decrease_trk_keep_alive_for_empty_masklets=False, + # Mask post-processing + fill_hole_area=16, + # Object tracking limits + max_num_objects=10000, + # Reconditioning parameters + recondition_every_nth_frame=16, + high_conf_thresh=0.8, + high_iou_thresh=0.8, + **kwargs, + ): + super().__init__(**kwargs) + + # Initialize detector config (Sam3) + if detector_config is None: + detector_config = {} + logger.info("detector_config is None. Initializing the Sam3Config with default values.") + if isinstance(detector_config, dict): + detector_config["model_type"] = detector_config.get("model_type", "sam3") + self.detector_config = CONFIG_MAPPING[detector_config["model_type"]](**detector_config) + elif isinstance(detector_config, PreTrainedConfig): + self.detector_config = detector_config + else: + raise ValueError(f"detector_config must be a dict or Sam3Config, got {type(detector_config)}") + + # Initialize tracker config (Sam2Video) + if tracker_config is None: + tracker_config = {} + logger.info("tracker_config is None. Initializing the Sam3TrackerVideoConfig with default values.") + if isinstance(tracker_config, dict): + tracker_config["model_type"] = tracker_config.get("model_type", "sam3_tracker_video") + self.tracker_config = CONFIG_MAPPING[tracker_config["model_type"]](**tracker_config) + elif isinstance(tracker_config, PreTrainedConfig): + self.tracker_config = tracker_config + else: + raise ValueError(f"tracker_config must be a dict or Sam3TrackerVideoConfig, got {type(tracker_config)}") + + # Model initialization + self.initializer_range = initializer_range + + self.low_res_mask_size = low_res_mask_size + + # Detection-tracking fusion hyperparameters + self.score_threshold_detection = score_threshold_detection + self.det_nms_thresh = det_nms_thresh + self.assoc_iou_thresh = assoc_iou_thresh + self.trk_assoc_iou_thresh = trk_assoc_iou_thresh + self.new_det_thresh = new_det_thresh + + self.recondition_on_trk_masks = recondition_on_trk_masks + + # Hotstart parameters + if hotstart_delay > 0: + if hotstart_unmatch_thresh > hotstart_delay: + raise ValueError( + f"hotstart_unmatch_thresh ({hotstart_unmatch_thresh}) must be <= hotstart_delay ({hotstart_delay})" + ) + if hotstart_dup_thresh > hotstart_delay: + raise ValueError( + f"hotstart_dup_thresh ({hotstart_dup_thresh}) must be <= hotstart_delay ({hotstart_delay})" + ) + self.hotstart_delay = hotstart_delay + self.hotstart_unmatch_thresh = hotstart_unmatch_thresh + self.hotstart_dup_thresh = hotstart_dup_thresh + self.suppress_unmatched_only_within_hotstart = suppress_unmatched_only_within_hotstart + + # Keep-alive parameters + self.init_trk_keep_alive = init_trk_keep_alive + self.max_trk_keep_alive = max_trk_keep_alive + self.min_trk_keep_alive = min_trk_keep_alive + + # Occlusion and overlap handling + self.suppress_overlapping_based_on_recent_occlusion_threshold = ( + suppress_overlapping_based_on_recent_occlusion_threshold + ) + self.decrease_trk_keep_alive_for_empty_masklets = decrease_trk_keep_alive_for_empty_masklets + + # Mask post-processing + self.fill_hole_area = fill_hole_area + + # Object tracking limits + self.max_num_objects = max_num_objects + + # Reconditioning parameters + self.recondition_every_nth_frame = recondition_every_nth_frame + self.high_conf_thresh = high_conf_thresh + self.high_iou_thresh = high_iou_thresh + + @property + def image_size(self): + """Image size for the video model.""" + return self.detector_config.image_size + + @image_size.setter + def image_size(self, value): + """Recursively propagate the image size to detector and tracker configs.""" + self.detector_config.image_size = value + self.tracker_config.image_size = value + + +__all__ = ["Sam3VideoConfig"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam3_video/modeling_sam3_video.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam3_video/modeling_sam3_video.py new file mode 100644 index 0000000000000000000000000000000000000000..df6d7c028523a00abb228c4d499b3573de6e6490 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam3_video/modeling_sam3_video.py @@ -0,0 +1,2012 @@ +# Copyright 2025 The Meta AI Authors and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + + +from collections import OrderedDict, defaultdict +from collections.abc import Iterator +from copy import deepcopy +from dataclasses import dataclass +from typing import Any + +import torch +import torch.nn.functional as F +from torch import Tensor +from tqdm.auto import tqdm + +from transformers.models.sam3.modeling_sam3 import Sam3VisionNeck + +from ...modeling_utils import PreTrainedModel +from ...utils import ModelOutput, auto_docstring, is_kernels_available, logging +from ..auto import AutoModel +from .configuration_sam3_video import Sam3VideoConfig + + +if is_kernels_available(): + from ...integrations.hub_kernels import get_kernel + +logger = logging.get_logger(__name__) + +cv_utils_kernel = None # None = not attempted, False = failed, kernel object = success + + +def _load_cv_utils_kernel_once(): + """Load cv_utils_kernel once on first use.""" + global cv_utils_kernel + if cv_utils_kernel is not None: + return # Already attempted loading (successfully or not) + + if not is_kernels_available(): + logger.warning_once( + "kernels library is not installed. NMS post-processing, hole filling, and sprinkle removal will be skipped. " + "Install it with `pip install kernels` for better mask quality." + ) + cv_utils_kernel = False + return + + try: + cv_utils_kernel = get_kernel("kernels-community/cv-utils") + except Exception as e: + logger.warning_once( + f"Failed to load cv_utils kernel (your torch/cuda setup may not be supported): {e}. " + "NMS post-processing, hole filling, and sprinkle removal will be skipped." + ) + cv_utils_kernel = False + + +class Sam3VideoInferenceCache: + """Cache for vision features and model constants.""" + + def __init__( + self, + inference_device: torch.device | str = "cpu", + inference_state_device: torch.device | str = "cpu", + max_vision_features_cache_size: int = 1, + ): + self.inference_device = inference_device + self.inference_state_device = inference_state_device + self.max_vision_features_cache_size = max_vision_features_cache_size + + self._vision_features = {} + + def cache_vision_features(self, frame_idx: int, features: dict): + """Cache vision features with automatic device management.""" + cached = {} + if len(self._vision_features) >= self.max_vision_features_cache_size: + # remove the oldest frame + self._vision_features.pop(min(self._vision_features.keys())) + + for key, value in features.items(): + if isinstance(value, torch.Tensor): + cached[key] = value.to(self.inference_state_device, non_blocking=True) + elif isinstance(value, (list, tuple)) and value and isinstance(value[0], torch.Tensor): + cached[key] = [v.to(self.inference_state_device, non_blocking=True) for v in value] + else: + cached[key] = value + self._vision_features[frame_idx] = cached + + def get_vision_features(self, frame_idx: int) -> dict | None: + """Get cached vision features, automatically moved to inference device.""" + if frame_idx not in self._vision_features: + return None + + cached = self._vision_features[frame_idx] + moved = {} + for key, value in cached.items(): + if isinstance(value, torch.Tensor): + moved[key] = value.to(self.inference_device, non_blocking=True) + elif isinstance(value, (list, tuple)) and value and isinstance(value[0], torch.Tensor): + moved[key] = [v.to(self.inference_device, non_blocking=True) for v in value] + else: + moved[key] = value + return moved + + def clear_all(self): + """Clear all cached data.""" + self._vision_features.clear() + + +class Sam3VideoInferenceSession: + r""" + Manages video inference session parameters, state and cache. + + Args: + video (`torch.FloatTensor`, *optional*): + The video to process. No need to provide when streaming. + video_height (`int`, *optional*): + The height of the video. + video_width (`int`, *optional*): + The width of the video. + inference_device (`torch.device`, *optional*, defaults to `"cpu"`): + The device to use for inference. + inference_state_device (`torch.device`, *optional*, defaults to `"cpu"`): + The device to store the inference state on. + video_storage_device (`torch.device`, *optional*, defaults to `"cpu"`): + The device to store the video on. + dtype (`torch.dtype`, *optional*, defaults to `"float32"`): + The dtype to use for the video. + max_vision_features_cache_size (`int`, *optional*, defaults to 1): + The maximum number of vision features to cache. + """ + + def __init__( + self, + video: torch.FloatTensor | None = None, + video_height: int | None = None, + video_width: int | None = None, + inference_device: torch.device | str = "cpu", + inference_state_device: torch.device | str = "cpu", + video_storage_device: torch.device | str = "cpu", + dtype: torch.dtype | str = "float32", + max_vision_features_cache_size: int = 1, + ): + # store as a dictionary to avoid double memory allocation with torch.cat when adding new frames + self.processed_frames = ( + dict(enumerate(video.to(video_storage_device, dtype=dtype))) if video is not None else None + ) + self.video_height = video_height + self.video_width = video_width + + self.inference_device = inference_device + self.inference_state_device = inference_state_device + self.video_storage_device = video_storage_device + self.dtype = dtype + self.max_vision_features_cache_size = max_vision_features_cache_size + + # Cache for computed features + self.cache = Sam3VideoInferenceCache( + inference_device=self.inference_device, + inference_state_device=self.inference_state_device, + max_vision_features_cache_size=self.max_vision_features_cache_size, + ) + + # Persistent object tracking state + self._obj_id_to_idx = OrderedDict() + self._obj_idx_to_id = OrderedDict() + self.obj_ids = [] + + self.mask_inputs_per_obj = {} + self.point_inputs_per_obj = {} + + # Persistent model outputs/history + self.output_dict_per_obj = {} + self.frames_tracked_per_obj = {} + + # Multi-prompt support + self.prompts = {} # prompt_id -> prompt_text + self.prompt_input_ids = {} # prompt_id -> input_ids + self.prompt_embeddings = {} # prompt_id -> text embeddings + self.prompt_attention_masks = {} # prompt_id -> attention_mask + self.obj_id_to_prompt_id = {} # obj_id -> prompt_id (assigned at detection time) + + # Tracking metadata for detection-tracking fusion + self.obj_id_to_score = {} # Detection scores per object + self.obj_id_to_tracker_score_frame_wise = defaultdict(dict) # Frame-wise tracker scores + self.obj_id_to_last_occluded = {} # Last occlusion frame per object + self.max_obj_id = -1 # Maximum object ID assigned so far (-1 means no object has been assigned yet) + + # Hotstart metadata + self.obj_first_frame_idx = {} # First frame index per object + self.unmatched_frame_inds = defaultdict(list) # Unmatched frame indices per object + self.overlap_pair_to_frame_inds = defaultdict(list) # Overlap tracking for duplicate detection + self.trk_keep_alive = {} # Keep-alive counters per object + self.removed_obj_ids = set() # Set of removed object IDs + self.suppressed_obj_ids = defaultdict(set) # Suppressed object IDs per frame + self.hotstart_removed_obj_ids = set() # Set of removed object IDs during hotstart + + # Output buffering for hotstart delay + self.output_buffer = [] + + @property + def num_frames(self) -> int | None: + """Number of frames in the video.""" + return len(self.processed_frames) if self.processed_frames is not None else None + + def add_prompt(self, prompt_text: str) -> int: + """ + Add a text prompt to the session and return its unique ID. + If the prompt already exists, returns the existing ID. + """ + for prompt_id, text in self.prompts.items(): + if text == prompt_text: + return prompt_id + + prompt_id = len(self.prompts) + self.prompts[prompt_id] = prompt_text + return prompt_id + + # Object management + def obj_id_to_idx(self, obj_id: int) -> int: + """Map object ID to index, creating new entry if needed.""" + if obj_id not in self._obj_id_to_idx: + obj_idx = len(self._obj_id_to_idx) + self._obj_id_to_idx[obj_id] = obj_idx + self._obj_idx_to_id[obj_idx] = obj_id + self.obj_ids.append(obj_id) + + self.mask_inputs_per_obj[obj_idx] = {} + self.point_inputs_per_obj[obj_idx] = {} + self.output_dict_per_obj[obj_idx] = { + "cond_frame_outputs": {}, + "non_cond_frame_outputs": {}, + } + self.frames_tracked_per_obj[obj_idx] = {} + return self._obj_id_to_idx[obj_id] + + # Video Inference specific functions + def obj_idx_to_id(self, obj_idx: int) -> int: + """Map model-side object index to client-side object id.""" + return self._obj_idx_to_id[obj_idx] + + def get_obj_num(self) -> int: + """Get the total number of unique object ids received so far in this session.""" + return len(self._obj_idx_to_id) + + def add_mask_inputs(self, obj_idx: int, frame_idx: int, inputs: torch.Tensor): + """Add mask inputs with automatic device placement.""" + self.mask_inputs_per_obj[obj_idx][frame_idx] = inputs.to( + self.inference_device, dtype=self.dtype, non_blocking=True + ) + + def remove_mask_inputs(self, obj_idx: int, frame_idx: int): + """Remove mask inputs.""" + self.mask_inputs_per_obj[obj_idx].pop(frame_idx, None) + + def remove_object(self, obj_id: int, strict: bool = False): + """ + Remove an object from the inference session. This would remove the object from + all frames in the video. + + Args: + obj_id (`int`): The object ID to remove. + strict (`bool`, *optional*, defaults to `False`): Whether to raise an error if the object doesn't exist. + """ + old_obj_idx_to_rm = self._obj_id_to_idx.get(obj_id, None) + # Check whether this object_id to remove actually exists and possibly raise an error. + if old_obj_idx_to_rm is None: + if not strict: + return + raise RuntimeError( + f"Cannot remove object id {obj_id} as it doesn't exist. All existing object ids: {self.obj_ids}." + ) + + # Clean up prompt mapping + self.obj_id_to_prompt_id.pop(obj_id, None) + + # If this is the only remaining object id, we simply reset the state. + if len(self._obj_id_to_idx) == 1: + self.reset_inference_session() + return + + # Step 1: Update the object id mapping (note that it must be done after Step 0, + # since Step 0 still requires the old object id mappings in inference_state) + old_obj_ids = self.obj_ids + old_obj_inds = list(range(len(old_obj_ids))) + remain_old_obj_inds = old_obj_inds.copy() + remain_old_obj_inds.remove(old_obj_idx_to_rm) + new_obj_ids = [old_obj_ids[old_idx] for old_idx in remain_old_obj_inds] + new_obj_inds = list(range(len(new_obj_ids))) + # build new mappings + old_idx_to_new_idx = dict(zip(remain_old_obj_inds, new_obj_inds)) + self._obj_id_to_idx = dict(zip(new_obj_ids, new_obj_inds)) + self._obj_idx_to_id = dict(zip(new_obj_inds, new_obj_ids)) + self.obj_ids = new_obj_ids + + # Step 2: For per-object tensor storage, we shift their obj_idx in the dict keys. + def _map_keys(container): + new_kvs = [] + for k in old_obj_inds: + v = container.pop(k) + if k in old_idx_to_new_idx: + new_kvs.append((old_idx_to_new_idx[k], v)) + container.update(new_kvs) + + _map_keys(self.point_inputs_per_obj) + _map_keys(self.mask_inputs_per_obj) + _map_keys(self.output_dict_per_obj) + _map_keys(self.frames_tracked_per_obj) + + # Output management with smart device placement + def store_output( + self, + obj_idx: int, + frame_idx: int, + output_key: str | None = None, + output_value: torch.Tensor | dict | None = None, + is_conditioning_frame: bool = True, + ): + """ + Store output with smart device management. + If output_key is None, the output is stored as a dictionary. + + Args: + obj_idx (int): The index of the object. + frame_idx (int): The index of the frame. + output_key (Optional[str]): The key of the output. If None, the output is stored as a dictionary. + output_value (Optional[Union[torch.Tensor, dict]]): The value of the output. + is_conditioning_frame (bool): Whether the output is for a conditioning frame. + """ + storage_key = "cond_frame_outputs" if is_conditioning_frame else "non_cond_frame_outputs" + + if output_key is None and isinstance(output_value, dict): + self.output_dict_per_obj[obj_idx][storage_key][frame_idx] = {} + for key, value in output_value.items(): + self.store_output(obj_idx, frame_idx, key, value, is_conditioning_frame) + return + + # Device placement: small tensors stay on inference device, large ones go to inference state device + if output_key in ["object_pointer", "object_score_logits"]: # Small tensors + self.output_dict_per_obj[obj_idx][storage_key][frame_idx][output_key] = output_value + elif isinstance(output_value, torch.Tensor): # Large tensors like masks, features + self.output_dict_per_obj[obj_idx][storage_key][frame_idx][output_key] = output_value.to( + self.inference_state_device, non_blocking=True + ) + else: + self.output_dict_per_obj[obj_idx][storage_key][frame_idx][output_key] = output_value + + def get_output( + self, + obj_idx: int, + frame_idx: int, + output_key: str, + is_conditioning_frame: bool = True, + ): + """ + Get output with smart device management. + + Args: + obj_idx (int): The index of the object. + frame_idx (int): The index of the frame. + output_key (str): The key of the output. + is_conditioning_frame (bool): Whether the output is for a conditioning frame. + """ + storage_key = "cond_frame_outputs" if is_conditioning_frame else "non_cond_frame_outputs" + out = self.output_dict_per_obj[obj_idx][storage_key].get(frame_idx, None) + # move to inference device if needed + if out is None: + return None + value = out[output_key] + if isinstance(value, torch.Tensor): + value = value.to(self.inference_device, non_blocking=True) + return value + + # Video frame management + def add_new_frame(self, pixel_values: torch.Tensor, frame_idx: int | None = None) -> int: + """Add new frame with automatic device placement.""" + pixel_values = pixel_values.to(self.video_storage_device, dtype=self.dtype, non_blocking=True) + if pixel_values.dim() == 4: + pixel_values = pixel_values.squeeze(0) + + if frame_idx is None: + frame_idx = len(self.processed_frames) if self.processed_frames is not None else 0 + + if self.processed_frames is None: + self.processed_frames = {frame_idx: pixel_values} + else: + self.processed_frames[frame_idx] = pixel_values + + return frame_idx + + def get_frame(self, frame_idx: int) -> torch.Tensor: + """Get frame from video.""" + return self.processed_frames[frame_idx].to(self.inference_device, non_blocking=True) + + def reset_tracking_data(self): + """Reset tracking data but keep cache.""" + self._obj_id_to_idx.clear() + self._obj_idx_to_id.clear() + self.obj_ids.clear() + self.output_dict_per_obj.clear() + self.frames_tracked_per_obj.clear() + # Note: cache and video data are preserved + + # Reset prompt mappings for objects (but keep prompts themselves) + self.obj_id_to_prompt_id.clear() + + def reset_inference_session(self): + """Reset tracking data and cache.""" + self._obj_id_to_idx.clear() + self._obj_idx_to_id.clear() + self.obj_ids.clear() + self.output_dict_per_obj.clear() + self.frames_tracked_per_obj.clear() + self.cache.clear_all() + + # Reset prompt mappings for objects (but keep prompts themselves) + self.obj_id_to_prompt_id.clear() + + def reset_state(self): + """Reset the inference session state.""" + self._obj_id_to_idx = OrderedDict() + self._obj_idx_to_id = OrderedDict() + self.obj_ids = [] + self.output_dict_per_obj = {} + self.frames_tracked_per_obj = {} + + # Reset detection-tracking fusion state + self.obj_id_to_score = {} + self.obj_id_to_tracker_score_frame_wise = defaultdict(dict) + self.obj_id_to_last_occluded = {} + self.max_obj_id = 0 + self.obj_first_frame_idx = {} + self.unmatched_frame_inds = defaultdict(list) + self.overlap_pair_to_frame_inds = defaultdict(list) + self.trk_keep_alive = {} + self.removed_obj_ids = set() + self.suppressed_obj_ids = defaultdict(set) + self.output_buffer = [] + + # Reset multi-prompt state + self.prompts.clear() + self.prompt_input_ids.clear() + self.prompt_embeddings.clear() + self.prompt_attention_masks.clear() + self.obj_id_to_prompt_id.clear() + + # Clear cache + self.cache.clear_all() + + +@dataclass +@auto_docstring(custom_intro="Base class for the Sam3Video model's output.") +class Sam3VideoSegmentationOutput(ModelOutput): + r""" + object_ids (`list[int]`, *optional*): + List of object IDs being tracked in the current frame. + obj_id_to_mask (`dict[int, torch.FloatTensor]`, *optional*): + Dictionary mapping object IDs to their predicted low-resolution masks. + Each mask has shape `(1, H_low, W_low)`. + obj_id_to_score (`dict[int, float]`, *optional*): + Dictionary mapping object IDs to their detection scores. + obj_id_to_tracker_score (`dict[int, float]`, *optional*): + Dictionary mapping object IDs to their tracker scores for the current frame. + removed_obj_ids (`set[int]`, *optional*): + Set of object IDs that have been removed (e.g., via hotstart heuristics). + suppressed_obj_ids (`set[int]`, *optional*): + Set of object IDs that have been suppressed in the current frame. + frame_idx (`int`, *optional*): + The frame index of the video. + """ + + object_ids: list[int] | None = None + obj_id_to_mask: dict[int, torch.FloatTensor] | None = None + obj_id_to_score: dict[int, float] | None = None + obj_id_to_tracker_score: dict[int, float] | None = None + removed_obj_ids: set[int] | None = None + suppressed_obj_ids: set[int] | None = None + frame_idx: int | None = None + + +class Sam3VideoPreTrainedModel(PreTrainedModel): + """ + An abstract class to handle weights initialization and a simple interface for downloading and loading pretrained + models. + """ + + config_class = Sam3VideoConfig + base_model_prefix = "sam3_video" + main_input_name = "pixel_values" + input_modalities = ["video", "text"] + _supports_sdpa = True + _supports_flash_attn = True + _supports_flex_attn = True + _supports_attention_backend = True + + +@auto_docstring +class Sam3VideoModel(Sam3VideoPreTrainedModel): + def __init__(self, config: Sam3VideoConfig): + super().__init__(config) + self.config = config + self.detector_model = AutoModel.from_config(config.detector_config) + self.tracker_model = AutoModel.from_config(config.tracker_config, remove_vision_encoder=True) + self.low_res_mask_size = config.low_res_mask_size + self.score_threshold_detection = config.score_threshold_detection + self.det_nms_thresh = config.det_nms_thresh + self.assoc_iou_thresh = config.assoc_iou_thresh + self.trk_assoc_iou_thresh = config.trk_assoc_iou_thresh + self.new_det_thresh = config.new_det_thresh + self.recondition_on_trk_masks = config.recondition_on_trk_masks + # hotstart parameters + self.hotstart_delay = config.hotstart_delay + self.hotstart_unmatch_thresh = config.hotstart_unmatch_thresh + self.hotstart_dup_thresh = config.hotstart_dup_thresh + self.suppress_unmatched_only_within_hotstart = config.suppress_unmatched_only_within_hotstart + self.init_trk_keep_alive = config.init_trk_keep_alive + self.max_trk_keep_alive = config.max_trk_keep_alive + self.min_trk_keep_alive = config.min_trk_keep_alive + self.suppress_overlapping_based_on_recent_occlusion_threshold = ( + config.suppress_overlapping_based_on_recent_occlusion_threshold + ) + self.decrease_trk_keep_alive_for_empty_masklets = config.decrease_trk_keep_alive_for_empty_masklets + self.fill_hole_area = config.fill_hole_area + self.eval() + + # the maximum object number + self.max_num_objects = config.max_num_objects + self.recondition_every_nth_frame = config.recondition_every_nth_frame + self.high_conf_thresh = config.high_conf_thresh + self.high_iou_thresh = config.high_iou_thresh + + self.tracker_neck = Sam3VisionNeck(config.detector_config.vision_config) + + self.post_init() + + def get_vision_features_for_tracker(self, vision_embeds: torch.Tensor): + hidden_states = vision_embeds.last_hidden_state + batch_size = hidden_states.shape[0] + height, width = self.tracker_model.prompt_encoder.image_embedding_size + hidden_states_spatial = hidden_states.view(batch_size, height, width, -1).permute(0, 3, 1, 2) + + fpn_hidden_states, fpn_position_encoding = self.tracker_neck(hidden_states_spatial) + + # precompute projected level 0 and level 1 features in SAM decoder + # to avoid running it again on every SAM click + feature_maps = list(fpn_hidden_states[:-1]) + feature_maps[0] = self.tracker_model.mask_decoder.conv_s0(feature_maps[0]) + feature_maps[1] = self.tracker_model.mask_decoder.conv_s1(feature_maps[1]) + + # flatten NxCxHxW to HWxNxC + feature_maps = [feature_map.flatten(2).permute(2, 0, 1) for feature_map in feature_maps] + feature_maps_position_embeddings = [ + feature_map_position_embedding.flatten(2).permute(2, 0, 1) + for feature_map_position_embedding in fpn_position_encoding[:-1] + ] + return feature_maps, feature_maps_position_embeddings + + def run_detection( + self, + inference_session: Sam3VideoInferenceSession, + vision_embeds: torch.Tensor, + ): + """ + Run detection for all prompts efficiently by reusing vision embeddings. + + Args: + inference_session: The inference session containing prompts and state + vision_embeds: Pre-computed vision embeddings to reuse across prompts + + Returns: + Dictionary mapping prompt_id to detection outputs + """ + prompt_ids = list(inference_session.prompts.keys()) + if not prompt_ids: + raise ValueError("No prompts available for detection. Please add prompts to the session first.") + + all_detections = {} + + for prompt_id in prompt_ids: + # Get or compute text embeddings for this prompt + if prompt_id not in inference_session.prompt_embeddings: + text_embeds = self.detector_model.get_text_features( + input_ids=inference_session.prompt_input_ids[prompt_id], + attention_mask=inference_session.prompt_attention_masks[prompt_id], + return_dict=True, + ).pooler_output + inference_session.prompt_embeddings[prompt_id] = text_embeds + else: + text_embeds = inference_session.prompt_embeddings[prompt_id] + + # Run detector with cached vision features (efficient!) + detector_outputs = self.detector_model( + vision_embeds=vision_embeds, + text_embeds=text_embeds, + attention_mask=inference_session.prompt_attention_masks[prompt_id], + ) + + pred_logits = detector_outputs.pred_logits + presence_logits = detector_outputs.presence_logits + + pred_probs = pred_logits.sigmoid() + presence_scores = presence_logits.sigmoid() + pred_probs = pred_probs * presence_scores + + run_nms = self.det_nms_thresh > 0.0 + if run_nms: + keep = nms_masks( + pred_probs=pred_probs[0], + pred_masks=detector_outputs.pred_masks[0], + prob_threshold=self.score_threshold_detection, + iou_threshold=self.det_nms_thresh, + ) + # Set suppressed detections' probabilities to 0 + pred_probs[0][~keep] = 0.0 + + pred_boxes_xyxy = detector_outputs.pred_boxes + pred_masks = detector_outputs.pred_masks + # get the positive detection outputs above threshold + pos_pred_idx = torch.where(pred_probs > self.score_threshold_detection) + det_out = { + "bbox": pred_boxes_xyxy[pos_pred_idx[0], pos_pred_idx[1]], + "mask": pred_masks[pos_pred_idx[0], pos_pred_idx[1]], + "scores": pred_probs[pos_pred_idx[0], pos_pred_idx[1]], + } + + all_detections[prompt_id] = det_out + + return all_detections + + def run_tracker_propagation( + self, + inference_session: Sam3VideoInferenceSession, + frame_idx: int, + reverse: bool, + ): + low_res_masks_list = [] + obj_scores_list = [] + if len(inference_session.obj_ids) > 0: + # propagate one frame + out = self.tracker_model( + inference_session=inference_session, + frame_idx=frame_idx, + reverse=reverse, + run_mem_encoder=False, + ) + out_low_res_masks = out.pred_masks + out_obj_scores = out.object_score_logits + + # only 1 frames should be propagated + low_res_masks_list.append(out_low_res_masks.squeeze(1)) + obj_scores_list.append(out_obj_scores.squeeze(1)) + + # concatenate the output masklets from all local inference states + H_mask = W_mask = self.low_res_mask_size + if len(low_res_masks_list) > 0: + low_res_masks = torch.cat(low_res_masks_list, dim=0) + obj_scores = torch.cat(obj_scores_list, dim=0) + + # Apply hole filling to the masks + low_res_masks = fill_holes_in_mask_scores( + low_res_masks.unsqueeze(1), + max_area=self.fill_hole_area, + fill_holes=True, + remove_sprinkles=True, + ) + low_res_masks = low_res_masks.squeeze(1) + else: + low_res_masks = torch.zeros(0, H_mask, W_mask, device=self.device) + obj_scores = torch.zeros(0, device=self.device) + + return low_res_masks, obj_scores + + def _associate_det_trk( + self, + det_masks: Tensor, + det_scores: Tensor, + trk_masks: Tensor, + trk_obj_ids: list[int], + det_prompt_ids: torch.Tensor, + trk_prompt_ids: torch.Tensor, + ): + """ + Match detections on the current frame with the existing masklets. + + Args: + - det_masks: (N, H, W) tensor of predicted masks + - det_scores: (N,) tensor of detection scores + - trk_masks: (M, H, W) tensor of track masks + - trk_obj_ids: (M,) list of object IDs corresponding to trk_masks + - det_prompt_ids: (N,) tensor of prompt IDs for each detection. Prevents cross-prompt + associations by zeroing IoUs between detections and tracks from different prompts. + - trk_prompt_ids: (M,) tensor of prompt IDs for each tracked object. Prevents cross-prompt + associations by zeroing IoUs between detections and tracks from different prompts. + + Returns: + - new_det_out_inds: list of new object indices among in FA detection outputs + - unmatched_trk_obj_ids: list of existing masklet object IDs that are not matched + to any detections on this frame (for unmatched, we only count masklets with >0 area) + - det_to_matched_trk_obj_ids: dict[int, list[int]]: mapping from FA detection indices + to the list of matched tracklet object IDs + - empty_trk_obj_ids: list of existing masklet object IDs with zero area in SAM2 prediction + """ + iou_threshold = self.assoc_iou_thresh + iou_threshold_trk = self.trk_assoc_iou_thresh + new_det_thresh = self.new_det_thresh + + trk_obj_ids_tensor = ( + torch.tensor(trk_obj_ids, dtype=torch.long, device=det_masks.device) + if trk_obj_ids + else torch.empty(0, dtype=torch.long, device=det_masks.device) + ) + if trk_masks.size(0) == 0: + # all detections are new + new_det_out_inds = list(range(det_masks.size(0))) + unmatched_trk_obj_ids = [] + empty_trk_obj_ids = [] + det_to_matched_trk_obj_ids = {} + trk_id_to_max_iou_high_conf_det = {} + return ( + new_det_out_inds, + unmatched_trk_obj_ids, + det_to_matched_trk_obj_ids, + trk_id_to_max_iou_high_conf_det, + empty_trk_obj_ids, + ) + elif det_masks.size(0) == 0: + # all previous tracklets are unmatched if they have a non-zero area + new_det_out_inds = [] + trk_is_nonempty = (trk_masks > 0).any(dim=(1, 2)) # (M,) tensor + # Use tensor boolean indexing - elegant and avoids intermediate conversions + unmatched_trk_obj_ids = trk_obj_ids_tensor[trk_is_nonempty].tolist() + empty_trk_obj_ids = trk_obj_ids_tensor[~trk_is_nonempty].tolist() + det_to_matched_trk_obj_ids = {} + trk_id_to_max_iou_high_conf_det = {} + return ( + new_det_out_inds, + unmatched_trk_obj_ids, + det_to_matched_trk_obj_ids, + trk_id_to_max_iou_high_conf_det, + empty_trk_obj_ids, + ) + + det_masks_binary = det_masks > 0 + trk_masks_binary = trk_masks > 0 + ious = mask_iou(det_masks_binary, trk_masks_binary) # (N, M) tensor + + # Prevent cross-prompt associations by zeroing IoUs between different prompt groups. + prompt_match = det_prompt_ids.unsqueeze(1) == trk_prompt_ids.unsqueeze(0) + ious = torch.where(prompt_match, ious, torch.zeros_like(ious)) + + # trk_is_matched: for each track, True if matched to any detection above threshold + trk_is_matched = (ious >= iou_threshold_trk).any(dim=0) # (M,) + # Non-empty tracks not matched by Hungarian assignment above threshold are unmatched + trk_is_nonempty = trk_masks_binary.any(dim=(1, 2)) # (M,) + trk_is_unmatched = trk_is_nonempty & ~trk_is_matched # (M,) + # Use tensor boolean indexing directly - no intermediate conversions + unmatched_trk_obj_ids = trk_obj_ids_tensor[trk_is_unmatched].tolist() + empty_trk_obj_ids = trk_obj_ids_tensor[~trk_is_nonempty].tolist() + + # For detections: allow many tracks to match to the same detection (many-to-one) + # So, a detection is 'new' if it does not match any track above threshold + det_matches_any_trk = (ious >= iou_threshold).any(dim=1) # (N,) + is_new_det = (det_scores >= new_det_thresh) & ~det_matches_any_trk # (N,) + new_det_out_inds = torch.where(is_new_det)[0].tolist() + + # Build detection-to-track mappings using tensor operations + det_to_matched_trk_obj_ids = {} + trk_id_to_max_iou_high_conf_det = {} # trk id --> exactly one detection idx + det_to_max_iou_trk_idx = ious.argmax(dim=1) # (N,) + det_is_high_conf = (det_scores >= self.high_conf_thresh) & ~is_new_det # (N,) + det_max_iou = ious.max(dim=1)[0] # (N,) + det_is_high_iou = det_max_iou >= self.high_iou_thresh # (N,) + det_is_high_conf_and_iou = det_is_high_conf & det_is_high_iou # (N,) + high_conf_and_iou_mask = det_is_high_conf_and_iou # Keep as tensor + + for det_idx in range(det_masks.size(0)): + # Find which tracks match this detection using tensor boolean indexing + matched_trk_mask = ious[det_idx] >= iou_threshold # (M,) + det_to_matched_trk_obj_ids[det_idx] = trk_obj_ids_tensor[matched_trk_mask].tolist() + + if high_conf_and_iou_mask[det_idx].item(): + trk_idx = det_to_max_iou_trk_idx[det_idx].item() + trk_obj_id = trk_obj_ids_tensor[trk_idx].item() + trk_id_to_max_iou_high_conf_det[trk_obj_id] = det_idx + + return ( + new_det_out_inds, + unmatched_trk_obj_ids, + det_to_matched_trk_obj_ids, + trk_id_to_max_iou_high_conf_det, + empty_trk_obj_ids, + ) + + def _process_hotstart( + self, + inference_session: Sam3VideoInferenceSession, + frame_idx: int, + reverse: bool, + det_to_matched_trk_obj_ids: dict[int, list[int]], + new_det_obj_ids: list[int], + empty_trk_obj_ids: list[int], + unmatched_trk_obj_ids: list[int], + extra_metadata: dict[str, Any], + streaming: bool = False, + ): + """ + Handle hotstart heuristics to remove unmatched or duplicated objects. + + In streaming mode, hotstart removal logic is disabled since we don't have + future frames to make informed decisions about object removal. + """ + # obj_id --> first frame index where the object was detected + obj_first_frame_idx = extra_metadata["obj_first_frame_idx"] + # obj_id --> [mismatched frame indices] + unmatched_frame_inds = extra_metadata["unmatched_frame_inds"] + trk_keep_alive = extra_metadata["trk_keep_alive"] + # (first_appear_obj_id, obj_id) --> [overlap frame indices] + overlap_pair_to_frame_inds = extra_metadata["overlap_pair_to_frame_inds"] + # removed_obj_ids: object IDs that are suppressed via hot-start + removed_obj_ids = extra_metadata["removed_obj_ids"] + suppressed_obj_ids = extra_metadata["suppressed_obj_ids"][frame_idx] + + obj_ids_newly_removed = set() # object IDs to be newly removed on this frame + hotstart_diff = frame_idx - self.hotstart_delay if not reverse else frame_idx + self.hotstart_delay + + # Step 1: log the frame index where each object ID first appears + for obj_id in new_det_obj_ids: + if obj_id not in obj_first_frame_idx: + obj_first_frame_idx[obj_id] = frame_idx + trk_keep_alive[int(obj_id)] = self.init_trk_keep_alive + + matched_trks = set() + # We use the det-->tracks list to check for matched objects. Otherwise, we need to compute areas to decide whether they're occluded + for matched_trks_per_det in det_to_matched_trk_obj_ids.values(): + matched_trks.update({int(obj_id) for obj_id in matched_trks_per_det}) + for obj_id in matched_trks: + # NOTE: To minimize number of configurable params, we use the hotstart_unmatch_thresh to set the max value of trk_keep_alive + trk_keep_alive[int(obj_id)] = min(self.max_trk_keep_alive, trk_keep_alive[int(obj_id)] + 1) + for obj_id in unmatched_trk_obj_ids: + unmatched_frame_inds[obj_id].append(frame_idx) + # NOTE: To minimize number of configurable params, we use the hotstart_unmatch_thresh to set the min value of trk_keep_alive + # The max keep alive is 2x the min, means the model prefers to keep the prediction rather than suppress it if it was matched long enough. + trk_keep_alive[int(obj_id)] = max(self.min_trk_keep_alive, trk_keep_alive[int(obj_id)] - 1) + if self.decrease_trk_keep_alive_for_empty_masklets: + for obj_id in empty_trk_obj_ids: + # NOTE: To minimize number of configurable params, we use the hotstart_unmatch_thresh to set the min value of trk_keep_alive + trk_keep_alive[int(obj_id)] = max(self.min_trk_keep_alive, trk_keep_alive[int(obj_id)] - 1) + + # Step 2: removed tracks that has not matched with detections for `hotstart_unmatch_thresh` frames with hotstart period + # a) add unmatched frame indices for each existing object ID + # note that `unmatched_trk_obj_ids` contains those frames where the SAM2 output mask + # doesn't match any FA detection; it excludes those frames where SAM2 gives an empty mask + # b) remove a masklet if it first appears after `hotstart_diff` and is unmatched for more + # than `self.hotstart_unmatch_thresh` frames + # NOTE: In streaming mode, we skip hotstart removal logic since we don't have future frames + if not streaming: + for obj_id, frame_indices in unmatched_frame_inds.items(): + if obj_id in removed_obj_ids or obj_id in obj_ids_newly_removed: + continue # skip if the object is already removed + if len(frame_indices) >= self.hotstart_unmatch_thresh: + is_within_hotstart = (obj_first_frame_idx[obj_id] > hotstart_diff and not reverse) or ( + obj_first_frame_idx[obj_id] < hotstart_diff and reverse + ) + if is_within_hotstart: + obj_ids_newly_removed.add(obj_id) + logger.info( + f"Removing object {obj_id} at frame {frame_idx} " + f"since it is unmatched for frames: {frame_indices}" + ) + if ( + trk_keep_alive[obj_id] <= 0 # Object has not been matched for too long + and not self.suppress_unmatched_only_within_hotstart + and obj_id not in removed_obj_ids + and obj_id not in obj_ids_newly_removed + ): + logger.debug(f"Suppressing object {obj_id} at frame {frame_idx}, due to being unmatched") + suppressed_obj_ids.add(obj_id) + + # Step 3: removed tracks that overlaps with another track for `hotstart_dup_thresh` frames + # a) find overlaps tracks -- we consider overlap if they match to the same detection + # NOTE: In streaming mode, we still track overlaps for metadata but skip removal logic + for matched_trk_obj_ids in det_to_matched_trk_obj_ids.values(): + if len(matched_trk_obj_ids) < 2: + continue # only count detections that are matched to multiple (>=2) masklets + # if there are multiple matched track ids, we need to find the one that appeared first; + # these later appearing ids may be removed since they may be considered as duplicates + first_appear_obj_id = ( + min(matched_trk_obj_ids, key=lambda x: obj_first_frame_idx[x]) + if not reverse + else max(matched_trk_obj_ids, key=lambda x: obj_first_frame_idx[x]) + ) + for obj_id in matched_trk_obj_ids: + if obj_id != first_appear_obj_id: + key = (first_appear_obj_id, obj_id) + overlap_pair_to_frame_inds[key].append(frame_idx) + + # b) remove a masklet if it first appears after `hotstart_diff` and it overlaps with another + # masklet (that appears earlier) for more than `self.hotstart_dup_thresh` frames + # NOTE: In streaming mode, we skip hotstart removal logic since we don't have future frames + if not streaming: + for (first_obj_id, obj_id), frame_indices in overlap_pair_to_frame_inds.items(): + if obj_id in removed_obj_ids or obj_id in obj_ids_newly_removed: + continue # skip if the object is already removed + if (obj_first_frame_idx[obj_id] > hotstart_diff and not reverse) or ( + obj_first_frame_idx[obj_id] < hotstart_diff and reverse + ): + if len(frame_indices) >= self.hotstart_dup_thresh: + obj_ids_newly_removed.add(obj_id) + logger.info( + f"Removing object {obj_id} at frame {frame_idx} " + f"since it overlaps with another track {first_obj_id} at frames: {frame_indices}" + ) + + removed_obj_ids.update(obj_ids_newly_removed) + return obj_ids_newly_removed, extra_metadata + + def run_memory_encoder( + self, + inference_session: Sam3VideoInferenceSession, + frame_idx: int, + high_res_masks: torch.Tensor, + object_score_logits: torch.Tensor, + ): + """ + Run the memory encoder on `high_res_masks`. This is usually after applying + non-overlapping constraints to object scores. Since their scores changed, their + memory also need to be computed again with the memory encoder. + """ + # Retrieve correct image features + cached_features = inference_session.cache.get_vision_features(frame_idx) + current_vision_feats = cached_features["vision_feats"] + maskmem_features, maskmem_pos_enc = self.tracker_model._encode_new_memory( + current_vision_feats=current_vision_feats[-1], + pred_masks_high_res=high_res_masks, + object_score_logits=object_score_logits, + is_mask_from_pts=False, + ) + return maskmem_features, maskmem_pos_enc + + def _prepare_recondition_masks( + self, + inference_session: Sam3VideoInferenceSession, + frame_idx: int, + det_out: dict[str, Tensor], + trk_masks: Tensor, + trk_id_to_max_iou_high_conf_det: dict[int, int], + tracker_obj_scores_global: Tensor, + ) -> dict[int, Tensor]: + """ + Prepare high-resolution masks for reconditioned objects. + Returns a dict of obj_idx -> high_res_mask for objects that should be reconditioned. + + When recondition_on_trk_masks=True, uses detector as validation signal to strengthen tracker memory. + When False, uses detector to correct tracker drift by replacing with detection masks. + """ + reconditioned_masks = {} + reconditioned_obj_ids = set() + + for trk_obj_id, det_idx in trk_id_to_max_iou_high_conf_det.items(): + obj_idx = inference_session.obj_id_to_idx(trk_obj_id) + obj_score = tracker_obj_scores_global[obj_idx] + if obj_score <= self.high_conf_thresh: + continue + + if self.recondition_on_trk_masks: + # Validation mode: detector confirms tracker quality, strengthen memory with tracked mask + new_mask = trk_masks[obj_idx : obj_idx + 1].unsqueeze(1) + reconditioned_masks[obj_idx] = new_mask + reconditioned_obj_ids.add(trk_obj_id) + else: + # Correction mode: detector corrects drift, replace tracker mask with detection mask + new_mask = det_out["mask"][det_idx : det_idx + 1].unsqueeze(1) + reconditioned_masks[obj_idx] = new_mask >= 0.5 + reconditioned_obj_ids.add(trk_obj_id) + + return reconditioned_masks, reconditioned_obj_ids + + def _get_objects_to_suppress_based_on_most_recently_occluded( + self, + binary_low_res_masks: Tensor, + last_occluded: list[int], + obj_ids: list[int], + reverse: bool = False, + ): + # Suppress overlapping masks for objects that were most recently occluded + to_suppress = torch.zeros( + binary_low_res_masks.size(0), + device=binary_low_res_masks.device, + dtype=torch.bool, + ) + if len(obj_ids) <= 1: + return to_suppress + + iou = mask_iou(binary_low_res_masks, binary_low_res_masks) # [N,N] + + # Create masks for upper triangular matrix (i < j) and IoU threshold + mask_iou_thresh = iou >= self.suppress_overlapping_based_on_recent_occlusion_threshold + overlapping_pairs = torch.triu(mask_iou_thresh, diagonal=1) # [N,N] + + last_occ_expanded_i = last_occluded.unsqueeze(1) # (N, 1) + last_occ_expanded_j = last_occluded.unsqueeze(0) # (1, N) + # Suppress most recently occluded + cmp_op = torch.gt if not reverse else torch.lt + suppress_i_mask = ( + overlapping_pairs + & cmp_op(last_occ_expanded_i, last_occ_expanded_j) # (last_occ_expanded_i > last_occ_expanded_j) + & (last_occ_expanded_j > -1) # j can suppress i only if i was previously occluded + ) + suppress_j_mask = ( + overlapping_pairs + & cmp_op(last_occ_expanded_j, last_occ_expanded_i) + & (last_occ_expanded_i > -1) # i can suppress j only if j was previously occluded + ) + # Apply suppression + to_suppress = suppress_i_mask.any(dim=1) | suppress_j_mask.any(dim=0) + + return to_suppress + + def _suppress_overlapping_based_on_recent_occlusion( + self, + inference_session: Sam3VideoInferenceSession, + frame_idx: int, + tracker_low_res_masks_global: Tensor, + tracker_metadata_new: dict[str, Any], + obj_ids_newly_removed: set[int], + reverse: bool = False, + ): + """ + Suppress overlapping masks based on the most recent occlusion information. If an object is removed by hotstart, we always suppress it if it overlaps with any other object. + Args: + frame_idx (int): The current frame index. + tracker_low_res_masks_global (Tensor): The low-resolution masks for the current frame. + tracker_metadata_prev (Dict[str, Any]): The metadata from the previous frame. + tracker_metadata_new (Dict[str, Any]): The metadata for the current frame. + obj_ids_newly_removed (Set[int]): The object IDs that have been removed. + Return: + Tensor: The updated low-resolution masks with some objects suppressed. + """ + obj_ids_global = inference_session.obj_ids + binary_tracker_low_res_masks_global = tracker_low_res_masks_global > 0 + batch_size = tracker_low_res_masks_global.size(0) + if batch_size > 0: + NEVER_OCCLUDED = -1 + ALWAYS_OCCLUDED = 100000 # This value should be larger than any possible frame index, indicates that the object was removed by hotstart logic + last_occluded_prev = torch.cat( + [ + inference_session.obj_id_to_last_occluded.get( + obj_id, + torch.full( + (1,), + fill_value=(NEVER_OCCLUDED if obj_id not in obj_ids_newly_removed else ALWAYS_OCCLUDED), + device=binary_tracker_low_res_masks_global.device, + dtype=torch.long, + ), + ) + for obj_id in obj_ids_global + ], + dim=0, + ) + + prompt_ids_global = torch.tensor( + [inference_session.obj_id_to_prompt_id[obj_id] for obj_id in obj_ids_global], + device=binary_tracker_low_res_masks_global.device, + dtype=torch.long, + ) + to_suppress = torch.zeros( + batch_size, + device=binary_tracker_low_res_masks_global.device, + dtype=torch.bool, + ) + + # Only suppress overlaps within the same prompt group. + unique_prompts = prompt_ids_global.unique(sorted=True) + for prompt_id in unique_prompts: + prompt_mask = prompt_ids_global == prompt_id + prompt_indices = torch.nonzero(prompt_mask, as_tuple=True)[0] + if prompt_indices.numel() <= 1: + continue + + prompt_masks = binary_tracker_low_res_masks_global[prompt_indices] + prompt_last_occ = last_occluded_prev[prompt_indices] + prompt_obj_ids = [obj_ids_global[idx] for idx in prompt_indices.tolist()] + prompt_suppress = self._get_objects_to_suppress_based_on_most_recently_occluded( + prompt_masks, + prompt_last_occ, + prompt_obj_ids, + reverse, + ) + to_suppress[prompt_indices] = prompt_suppress + + # Update metadata with occlusion information + is_obj_occluded = ~(binary_tracker_low_res_masks_global.any(dim=(-1, -2))) + is_obj_occluded_or_suppressed = is_obj_occluded | to_suppress + last_occluded_new = last_occluded_prev.clone() + last_occluded_new[is_obj_occluded_or_suppressed] = frame_idx + # Slice out the last occluded frame for each object + tracker_metadata_new["obj_id_to_last_occluded"] = { + obj_id: last_occluded_new[obj_idx : obj_idx + 1] for obj_idx, obj_id in enumerate(obj_ids_global) + } + + # Zero out suppressed masks before memory encoding + NO_OBJ_LOGIT = -10 + tracker_low_res_masks_global[to_suppress] = NO_OBJ_LOGIT + + return tracker_low_res_masks_global + + def _apply_non_overlapping_constraints(self, pred_masks): + """ + Apply non-overlapping constraints to the object scores in pred_masks. Here we + keep only the highest scoring object at each spatial location in pred_masks. + """ + batch_size = pred_masks.size(0) + if batch_size == 1: + return pred_masks + + device = pred_masks.device + # "max_obj_inds": object index of the object with the highest score at each location + max_obj_inds = torch.argmax(pred_masks, dim=0, keepdim=True) + # "batch_obj_inds": object index of each object slice (along dim 0) in `pred_masks` + batch_obj_inds = torch.arange(batch_size, device=device)[:, None, None, None] + keep = max_obj_inds == batch_obj_inds + # suppress overlapping regions' scores below -10.0 so that the foreground regions + # don't overlap (here sigmoid(-10.0)=4.5398e-05) + pred_masks = torch.where(keep, pred_masks, torch.clamp(pred_masks, max=-10.0)) + return pred_masks + + def _suppress_shrinked_masks(self, pred_masks, new_pred_masks, shrink_threshold=0.3): + area_before = (pred_masks > 0).sum(dim=(-1, -2)) + area_after = (new_pred_masks > 0).sum(dim=(-1, -2)) + area_before = torch.clamp(area_before, min=1.0) + area_ratio = area_after / area_before + keep = area_ratio >= shrink_threshold + keep_mask = keep[..., None, None].expand_as(pred_masks) + pred_masks_after = torch.where(keep_mask, pred_masks, torch.clamp(pred_masks, max=-10.0)) + return pred_masks_after + + def _suppress_object_pw_area_shrinkage( + self, + pred_masks, + prompt_ids: list[int] | None = None, + ): + """ + This function suppresses masks that shrink in area after applying pixelwise non-overlapping constraints. + When `prompt_ids` are provided, constraints are enforced independently per prompt group. + """ + if prompt_ids is None: + return self._suppress_object_pw_area_shrinkage_impl(pred_masks) + + if len(prompt_ids) != pred_masks.size(0): + raise ValueError("prompt_ids must have the same length as pred_masks") + + prompt_ids_tensor = torch.tensor(prompt_ids, device=pred_masks.device, dtype=torch.long) + pred_masks_grouped = pred_masks.clone() + for prompt_id in prompt_ids_tensor.unique(sorted=True): + indices = torch.nonzero(prompt_ids_tensor == prompt_id, as_tuple=True)[0] + if indices.numel() == 0: + continue + pred_masks_grouped[indices] = self._suppress_object_pw_area_shrinkage_impl(pred_masks_grouped[indices]) + return pred_masks_grouped + + def _suppress_object_pw_area_shrinkage_impl(self, pred_masks): + if pred_masks.size(0) <= 1: + return pred_masks + + pixel_level_non_overlapping_masks = self._apply_non_overlapping_constraints(pred_masks) + pred_masks = self._suppress_shrinked_masks(pred_masks, pixel_level_non_overlapping_masks) + return pred_masks + + def _tracker_update_memories( + self, + inference_session: Sam3VideoInferenceSession, + frame_idx: int, + low_res_masks: Tensor, + reconditioned_masks: dict[int, Tensor] | None = None, + ): + """ + Run Sam3Tracker memory encoder, enforcing non-overlapping constraints globally. + Now with batched memory encoding for better performance. + + Args: + inference_session: The inference session state + frame_idx: Current frame index + low_res_masks: Low-resolution tracker masks for all objects + reconditioned_masks: Optional dict of obj_idx -> high_res_mask for objects that + should use detection masks instead of tracker masks + """ + if len(inference_session.obj_ids) == 0: + return + + if reconditioned_masks is None: + reconditioned_masks = {} + # Interpolate tracker masks to high resolution + high_res_masks = low_res_masks.unsqueeze(1) + + # Override with detection masks for reconditioned objects + for obj_idx, recond_mask in reconditioned_masks.items(): + high_res_masks[obj_idx] = recond_mask.float() + # Mark as conditioning frame for reconditioned objects + output_dict = inference_session.output_dict_per_obj[obj_idx] + if frame_idx in output_dict["non_cond_frame_outputs"]: + current_out = output_dict["non_cond_frame_outputs"].pop(frame_idx) + output_dict["cond_frame_outputs"][frame_idx] = current_out + + # Apply non-overlapping constraints before memory encoding. + # Constraints are enforced independently per prompt group. + # Every object ID has a prompt_id assigned when it's created. + prompt_ids_for_objects = [ + inference_session.obj_id_to_prompt_id[obj_id] for obj_id in inference_session.obj_ids + ] + high_res_masks = self._suppress_object_pw_area_shrinkage(high_res_masks, prompt_ids_for_objects) + # Use mask areas as a proxy for object scores + object_score_logits = torch.where((high_res_masks > 0).any(dim=(-1, -2)), 10.0, -10.0) + + # Run memory encoder in batch for all objects at once + num_objects = len(inference_session.obj_ids) + object_score_logits_batched = object_score_logits.unsqueeze(-1) # Shape: (num_objects, 1) + + # Encode memories for all objects in one batch call + maskmem_features_batched, maskmem_pos_enc_batched = self.run_memory_encoder( + inference_session, + frame_idx, + high_res_masks, # Shape: (num_objects, 1, H, W) + object_score_logits_batched, # Shape: (num_objects, 1) + ) + + # Split and store encoded memories per object + for obj_idx in range(num_objects): + output_dict = inference_session.output_dict_per_obj[obj_idx] + # Extract per-object memory from batched result + maskmem_features = maskmem_features_batched[:, obj_idx : obj_idx + 1] + maskmem_pos_enc = maskmem_pos_enc_batched[:, obj_idx : obj_idx + 1] + + for storage_key in ["cond_frame_outputs", "non_cond_frame_outputs"]: + if frame_idx not in output_dict[storage_key]: + continue + current_out = output_dict[storage_key][frame_idx] + current_out["maskmem_features"] = maskmem_features + current_out["maskmem_pos_enc"] = maskmem_pos_enc + + def run_tracker_update_planning_phase( + self, + inference_session: Sam3VideoInferenceSession, + frame_idx: int, + reverse: bool, + det_out: dict[str, Tensor], + tracker_low_res_masks_global: Tensor, + tracker_obj_scores_global: Tensor, + det_idx_to_prompt_id: dict[int, int], + streaming: bool = False, + ): + # initialize new metadata from previous metadata (its values will be updated later) + tracker_metadata_new = { + "obj_ids": deepcopy(inference_session.obj_ids), + "obj_id_to_score": deepcopy(inference_session.obj_id_to_score), + "obj_id_to_tracker_score_frame_wise": deepcopy(inference_session.obj_id_to_tracker_score_frame_wise), + "obj_id_to_last_occluded": {}, # will be filled later + "max_obj_id": deepcopy(inference_session.max_obj_id), + } + + # Initialize reconditioned_obj_ids early to avoid UnboundLocalError + reconditioned_obj_ids = set() + + # Step 1: make the update plan and resolve heuristics + det_mask_preds: Tensor = det_out["mask"] # low-res mask logits + det_scores: Tensor = det_out["scores"].float() # Keep as tensor! + # det_idx_to_prompt_id maps every detection index to its prompt_id (created by _merge_detections_from_prompts). + det_prompt_ids = ( + torch.tensor( + [det_idx_to_prompt_id[idx] for idx in range(det_mask_preds.size(0))], + device=det_mask_preds.device, + dtype=torch.long, + ) + if det_mask_preds.size(0) > 0 + else torch.empty(0, device=det_mask_preds.device, dtype=torch.long) + ) + # Get prompt IDs for tracked objects. + trk_prompt_ids = ( + torch.tensor( + [inference_session.obj_id_to_prompt_id[obj_id] for obj_id in inference_session.obj_ids], + device=tracker_low_res_masks_global.device + if tracker_low_res_masks_global.numel() > 0 + else det_mask_preds.device, + dtype=torch.long, + ) + if tracker_low_res_masks_global.numel() > 0 + else torch.empty(0, device=det_mask_preds.device, dtype=torch.long) + ) + # a) match FA and SAM2 masks and find new objects + ( + new_det_out_inds, + unmatched_trk_obj_ids, + det_to_matched_trk_obj_ids, + trk_id_to_max_iou_high_conf_det, + empty_trk_obj_ids, + ) = self._associate_det_trk( + det_masks=det_mask_preds, + det_scores=det_scores, + trk_masks=tracker_low_res_masks_global, + trk_obj_ids=inference_session.obj_ids, + det_prompt_ids=det_prompt_ids, + trk_prompt_ids=trk_prompt_ids, + ) + + # check whether we've hit the maximum number of objects we can track (and if so, drop some detections) + prev_obj_num = len(inference_session.obj_ids) + new_det_num = len(new_det_out_inds) + num_obj_dropped_due_to_limit = 0 + if prev_obj_num + new_det_num > self.max_num_objects: + logger.warning(f"hitting {self.max_num_objects=} with {new_det_num=} and {prev_obj_num=}") + new_det_num_to_keep = self.max_num_objects - prev_obj_num + num_obj_dropped_due_to_limit = new_det_num - new_det_num_to_keep + # Keep top scoring detections + new_det_inds_tensor = torch.tensor(new_det_out_inds, dtype=torch.long, device=det_scores.device) + scores_for_new_dets = det_scores[new_det_inds_tensor] + _, top_inds = torch.topk(scores_for_new_dets, k=new_det_num_to_keep, largest=True) + new_det_out_inds = [new_det_out_inds[i] for i in top_inds] + new_det_num = len(new_det_out_inds) + + # assign object IDs to new detections + new_det_start_obj_id = inference_session.max_obj_id + 1 + new_det_obj_ids = list(range(new_det_start_obj_id, new_det_start_obj_id + new_det_num)) + + # Assign prompt IDs to new objects based on which prompt detected them. + for obj_id, det_idx in zip(new_det_obj_ids, new_det_out_inds): + prompt_id = det_idx_to_prompt_id[det_idx] + inference_session.obj_id_to_prompt_id[obj_id] = prompt_id + + # b) handle hotstart heuristics to remove objects + extra_metadata_new = deepcopy( + { + "obj_first_frame_idx": inference_session.obj_first_frame_idx, + "unmatched_frame_inds": inference_session.unmatched_frame_inds, + "trk_keep_alive": inference_session.trk_keep_alive, + "overlap_pair_to_frame_inds": inference_session.overlap_pair_to_frame_inds, + "removed_obj_ids": inference_session.removed_obj_ids, + "suppressed_obj_ids": inference_session.suppressed_obj_ids, + } + ) + + obj_ids_newly_removed, extra_metadata_new = self._process_hotstart( + inference_session=inference_session, + frame_idx=frame_idx, + reverse=reverse, + det_to_matched_trk_obj_ids=det_to_matched_trk_obj_ids, + new_det_obj_ids=new_det_obj_ids, + empty_trk_obj_ids=empty_trk_obj_ids, + unmatched_trk_obj_ids=unmatched_trk_obj_ids, + extra_metadata=extra_metadata_new, + streaming=streaming, + ) + tracker_metadata_new["extra_metadata"] = extra_metadata_new + + # Step 3 (optional): prepare reconditioned masks based on high-confidence detections + reconditioned_masks = {} + reconditioned_obj_ids = set() + should_recondition_periodic = ( + self.recondition_every_nth_frame > 0 + and frame_idx % self.recondition_every_nth_frame == 0 + and len(trk_id_to_max_iou_high_conf_det) > 0 + ) + + if should_recondition_periodic: + reconditioned_masks, reconditioned_obj_ids = self._prepare_recondition_masks( + inference_session=inference_session, + frame_idx=frame_idx, + det_out=det_out, + trk_masks=tracker_low_res_masks_global, + trk_id_to_max_iou_high_conf_det=trk_id_to_max_iou_high_conf_det, + tracker_obj_scores_global=tracker_obj_scores_global, + ) + + tracker_update_plan = { + "new_det_out_inds": new_det_out_inds, # List[int] + "new_det_obj_ids": new_det_obj_ids, # List[int] + "unmatched_trk_obj_ids": unmatched_trk_obj_ids, # List[int] + "det_to_matched_trk_obj_ids": det_to_matched_trk_obj_ids, # dict + "obj_ids_newly_removed": obj_ids_newly_removed, # set + "num_obj_dropped_due_to_limit": num_obj_dropped_due_to_limit, # int + "trk_id_to_max_iou_high_conf_det": trk_id_to_max_iou_high_conf_det, # dict + "reconditioned_obj_ids": reconditioned_obj_ids, # set + } + + # Step 4: Run SAM2 memory encoder on the current frame's prediction masks + # This uses tracker masks for most objects, but detection masks for reconditioned objects + batch_size = tracker_low_res_masks_global.size(0) + if batch_size > 0: + if self.suppress_overlapping_based_on_recent_occlusion_threshold > 0.0: + # NOTE: tracker_low_res_masks_global is updated in-place then returned + tracker_low_res_masks_global = self._suppress_overlapping_based_on_recent_occlusion( + inference_session=inference_session, + frame_idx=frame_idx, + tracker_low_res_masks_global=tracker_low_res_masks_global, + tracker_metadata_new=tracker_metadata_new, + obj_ids_newly_removed=obj_ids_newly_removed, + reverse=reverse, + ) + + # Unified memory encoding: uses detection masks for reconditioned objects + self._tracker_update_memories( + inference_session=inference_session, + frame_idx=frame_idx, + low_res_masks=tracker_low_res_masks_global, + reconditioned_masks=reconditioned_masks, + ) + + # Step 5: update the SAM2 metadata based on the update plan + updated_obj_ids = tracker_metadata_new["obj_ids"] + if len(new_det_obj_ids) > 0: + updated_obj_ids = updated_obj_ids + new_det_obj_ids + if len(obj_ids_newly_removed) > 0: + updated_obj_ids = [obj_id for obj_id in updated_obj_ids if obj_id not in obj_ids_newly_removed] + tracker_metadata_new["obj_ids"] = updated_obj_ids + + # update object scores and the maximum object ID assigned so far + if len(new_det_obj_ids) > 0: + # Index tensor with list of indices and convert to list + new_det_scores = det_scores[ + torch.tensor(new_det_out_inds, dtype=torch.long, device=det_scores.device) + ].tolist() + tracker_metadata_new["obj_id_to_score"].update(zip(new_det_obj_ids, new_det_scores)) + # tracker scores are not available for new objects, use det score instead. + tracker_metadata_new["obj_id_to_tracker_score_frame_wise"][frame_idx].update( + zip(new_det_obj_ids, new_det_scores) + ) + tracker_metadata_new["max_obj_id"] = max( + tracker_metadata_new["max_obj_id"], + max(new_det_obj_ids), + ) + # for removed objects, we set their scores to a very low value (-1e4) but still + # keep them in "obj_id_to_score" (it's easier to handle outputs this way) + for obj_id in obj_ids_newly_removed: + tracker_metadata_new["obj_id_to_score"][obj_id] = -1e4 + tracker_metadata_new["obj_id_to_tracker_score_frame_wise"][frame_idx][obj_id] = -1e4 + tracker_metadata_new["obj_id_to_last_occluded"].pop(obj_id, None) + + return tracker_update_plan, tracker_metadata_new + + def _tracker_add_new_objects( + self, + inference_session: Sam3VideoInferenceSession, + frame_idx: int, + new_obj_ids: list[int], + new_obj_masks: Tensor, + reverse: bool = False, + ): + """Add a new object to SAM2 inference states.""" + new_obj_masks = new_obj_masks >= 0.5 + for obj_id, mask in zip(new_obj_ids, new_obj_masks): + obj_idx = inference_session.obj_id_to_idx(obj_id) + inference_session.add_mask_inputs(obj_idx, frame_idx, mask.unsqueeze(0).unsqueeze(0)) + + inference_session.obj_with_new_inputs = list(new_obj_ids) + + self.tracker_model( + inference_session=inference_session, + frame_idx=frame_idx, + reverse=reverse, + run_mem_encoder=True, + ) + + def run_tracker_update_execution_phase( + self, + inference_session: Sam3VideoInferenceSession, + frame_idx: int, + det_out: dict[str, Tensor], + tracker_update_plan: dict, + reverse: bool = False, + ): + # initialize tracking scores with detection scores + new_det_out_inds: list[int] = tracker_update_plan["new_det_out_inds"] + new_det_obj_ids: list[int] = tracker_update_plan["new_det_obj_ids"] + obj_ids_newly_removed: set[int] = tracker_update_plan["obj_ids_newly_removed"] + + # Step 1: add new objects from FA detection to SAM2 inference states + if len(new_det_out_inds) > 0: + new_det_out_inds_t = torch.tensor(new_det_out_inds, dtype=torch.long) + new_det_masks: Tensor = det_out["mask"][new_det_out_inds_t] + # initialize SAM2 with new object masks + self._tracker_add_new_objects( + inference_session=inference_session, + frame_idx=frame_idx, + new_obj_ids=new_det_obj_ids, + new_obj_masks=new_det_masks, + reverse=reverse, + ) + + # Step 2: remove from SAM2 inference states those objects removed by heuristics + for obj_id in obj_ids_newly_removed: + inference_session.remove_object(obj_id, strict=False) # implement remove_object in inference_session? + + def build_outputs( + self, + inference_session: Sam3VideoInferenceSession, + det_out: dict[str, Tensor], + tracker_low_res_masks_global: Tensor, + tracker_update_plan: dict, + reconditioned_obj_ids: set | None = None, + ): + """ + Build output dictionary with low-resolution masks. + Interpolation to video resolution is handled by the processor. + + Returns: + obj_id_to_mask: dict mapping obj_id to low-res mask tensor (1, H_low, W_low) + """ + new_det_out_inds: list[int] = tracker_update_plan["new_det_out_inds"] + new_det_obj_ids: list[int] = tracker_update_plan["new_det_obj_ids"] + obj_id_to_mask = {} # obj_id --> low-res mask tensor + + # Part 1: masks from tracker propagation (existing objects) + existing_masklet_obj_ids = inference_session.obj_ids + for obj_id, mask in zip(existing_masklet_obj_ids, tracker_low_res_masks_global): + obj_id_to_mask[int(obj_id)] = mask.unsqueeze(0) # (1, H_low, W_low) + + # Part 2: masks from new detections + if len(new_det_out_inds) > 0: + new_det_out_inds_t = torch.tensor(new_det_out_inds, dtype=torch.long, device=det_out["mask"].device) + new_det_low_res_masks = det_out["mask"][new_det_out_inds_t] + # Apply hole filling to new detection masks + new_det_low_res_masks = fill_holes_in_mask_scores( + new_det_low_res_masks.unsqueeze(1), + max_area=self.fill_hole_area, + fill_holes=True, + remove_sprinkles=True, + ).squeeze(1) + + for obj_id, mask in zip(new_det_obj_ids, new_det_low_res_masks): + obj_id_to_mask[int(obj_id)] = mask.unsqueeze(0) # (1, H_low, W_low) + + # Part 3: Override masks for reconditioned objects using detection masks + if reconditioned_obj_ids is not None and len(reconditioned_obj_ids) > 0: + trk_id_to_max_iou_high_conf_det = tracker_update_plan.get("trk_id_to_max_iou_high_conf_det", {}) + + for obj_id in reconditioned_obj_ids: + det_idx = trk_id_to_max_iou_high_conf_det.get(obj_id) + if det_idx is not None: + det_mask = det_out["mask"][det_idx].unsqueeze(0) # (1, H_low, W_low) + obj_id_to_mask[int(obj_id)] = det_mask + + return obj_id_to_mask + + def _merge_detections_from_prompts( + self, + all_detections: dict[int, dict[str, Tensor]], + inference_session: Sam3VideoInferenceSession, + ) -> tuple[dict[str, Tensor], dict[int, int]]: + """ + Merge detections from multiple prompts into a single detection output. + Assigns unique object IDs and tracks which prompt detected each object. + + Args: + all_detections: Dictionary mapping prompt_id to detection outputs + inference_session: Session to track obj_id -> prompt_id mapping + + Returns: + Tuple of (merged_det_out, det_idx_to_prompt_id) where det_idx_to_prompt_id + maps detection index in the merged output to the prompt that produced it. + """ + merged_bboxes, merged_masks, merged_scores = [], [], [] + det_idx_to_prompt_id = {} + det_idx = 0 + + for prompt_id, det_out in all_detections.items(): + num_dets = len(det_out["bbox"]) + if num_dets > 0: + merged_bboxes.append(det_out["bbox"]) + merged_masks.append(det_out["mask"]) + merged_scores.append(det_out["scores"]) + for i in range(num_dets): + det_idx_to_prompt_id[det_idx + i] = prompt_id + det_idx += num_dets + + if merged_bboxes: + merged_det_out = { + "bbox": torch.cat(merged_bboxes), + "mask": torch.cat(merged_masks), + "scores": torch.cat(merged_scores), + } + else: + device = inference_session.inference_device + merged_det_out = { + "bbox": torch.zeros(0, 4, device=device), + "mask": torch.zeros(0, self.low_res_mask_size, self.low_res_mask_size, device=device), + "scores": torch.zeros(0, device=device), + } + + return merged_det_out, det_idx_to_prompt_id + + def _det_track_one_frame( + self, + inference_session: Sam3VideoInferenceSession, + frame_idx: int, + reverse: bool, + streaming: bool = False, + ): + """ + This function handles one-step inference for the DenseTracking model. + + - `inference_session` contains all the information needed for inference, including the input video frames, text prompts, and any other relevant metadata + - The function processes detection and tracking for a single frame + - `streaming` indicates whether this is streaming inference mode (frames provided one at a time) + """ + + pixel_values = inference_session.get_frame(frame_idx).unsqueeze(0) + vision_embeds = self.detector_model.get_vision_features(pixel_values=pixel_values) + + # Step 1: run detection for all prompts (efficiently reusing vision embeddings) + # Returns dict mapping prompt_id to detection outputs + all_detections = self.run_detection( + inference_session=inference_session, + vision_embeds=vision_embeds, + ) + + # Merge detections from all prompts into single output for tracking + det_out, det_idx_to_prompt_id = self._merge_detections_from_prompts(all_detections, inference_session) + + # share the vision encoder outputs from the detector to the tracker + vision_feats, vision_pos_embeds = self.get_vision_features_for_tracker( + vision_embeds=vision_embeds, + ) + inference_session.cache.cache_vision_features( + frame_idx, {"vision_feats": vision_feats, "vision_pos_embeds": vision_pos_embeds} + ) + + # Step 2: propagate SAM2 states to get the SAM2 prediction masks. + # The returned `tracker_low_res_masks_global` contains the masklet predictions. + # Note that this step only runs the SAM2 propagation step, but doesn't encode new memory for the predicted masks; + # we defer memory encoding to `run_tracker_update_execution_phase` after resolving all heuristics. + tracker_low_res_masks_global, tracker_obj_scores_global = self.run_tracker_propagation( + inference_session=inference_session, frame_idx=frame_idx, reverse=reverse + ) + + # Step 3: based on detection outputs and the propagated SAM2 prediction masks, we make plans + # for SAM2 masklet updates (i.e. which objects to add and remove, etc). + # We also run SAM2 memory encoder in this step to resolve non-overlapping constraints. + # **This step should involve all the heuristics needed for any updates.** + # This step also generates the new masklet metadata `tracker_metadata_new` (based on its previous version). + tracker_update_plan, tracker_metadata_new = self.run_tracker_update_planning_phase( + inference_session=inference_session, + frame_idx=frame_idx, + reverse=reverse, + det_out=det_out, + tracker_low_res_masks_global=tracker_low_res_masks_global, + tracker_obj_scores_global=tracker_obj_scores_global, + det_idx_to_prompt_id=det_idx_to_prompt_id, + streaming=streaming, + ) + + # Step 4: based on `tracker_update_plan`, execute the update w.r.t. the tracker states + self.run_tracker_update_execution_phase( + inference_session=inference_session, + frame_idx=frame_idx, + reverse=reverse, + det_out=det_out, + tracker_update_plan=tracker_update_plan, + ) + + # Step 5: finally, build the outputs for this frame + reconditioned_obj_ids = tracker_update_plan["reconditioned_obj_ids"] + obj_id_to_mask = self.build_outputs( + inference_session=inference_session, + det_out=det_out, + tracker_low_res_masks_global=tracker_low_res_masks_global, + tracker_update_plan=tracker_update_plan, + reconditioned_obj_ids=reconditioned_obj_ids, + ) + obj_id_to_score = tracker_metadata_new["obj_id_to_score"] + # add tracker scores to metadata, it should be fired for frames except the first frame + if tracker_obj_scores_global.shape[0] > 0: + # Convert tracker_obj_scores_global to sigmoid scores before updating + tracker_obj_scores_global = tracker_obj_scores_global.sigmoid().tolist() + tracker_obj_ids = inference_session.obj_ids + tracker_metadata_new["obj_id_to_tracker_score_frame_wise"][frame_idx].update( + dict(zip(tracker_obj_ids, tracker_obj_scores_global)) + ) + + return ( + obj_id_to_mask, # a dict: obj_id --> output mask + obj_id_to_score, # a dict: obj_id --> output score (prob) + tracker_metadata_new, + tracker_obj_scores_global, # a dict: obj_id --> tracker frame-level scores + ) + + @torch.inference_mode() + @auto_docstring(custom_intro="Propagate the objects through a streamed video frame.") + def forward( + self, + inference_session: Sam3VideoInferenceSession, + frame_idx: int | None = None, + frame: torch.Tensor | None = None, + reverse: bool = False, + **kwargs, + ): + r""" + inference_session (`Sam3VideoInferenceSession`): + The video inference session object. + frame_idx (`int`, *optional*): + The index of the frame on which to run inference. No need to provide when inferring + on a new streamed frame. + frame (`torch.Tensor`, *optional*): + The frame to process. Provide when streaming. + reverse (`bool`, *optional*, defaults to `False`): + Whether to propagate in reverse. + """ + if frame is not None: + frame_idx = inference_session.add_new_frame(frame, frame_idx) + + if frame_idx is None: + raise ValueError("frame_idx must be provided when frame is not provided for streaming.") + + ( + obj_id_to_mask, + obj_id_to_score, + tracker_metadata_new, + _, + ) = self._det_track_one_frame( + inference_session=inference_session, + frame_idx=frame_idx, + reverse=reverse, + streaming=frame is not None, + ) + # use a dummy string in "previous_stages_out" to indicate this frame has outputs + # inference_session.previous_stages_out[frame_idx] = "_THIS_FRAME_HAS_OUTPUTS_" + + extra_metadata = tracker_metadata_new["extra_metadata"] + removed_obj_ids = extra_metadata["removed_obj_ids"] + + # Update inference session state + inference_session.obj_id_to_score = obj_id_to_score + inference_session.obj_id_to_tracker_score_frame_wise = tracker_metadata_new[ + "obj_id_to_tracker_score_frame_wise" + ] + inference_session.obj_id_to_last_occluded = tracker_metadata_new["obj_id_to_last_occluded"] + inference_session.max_obj_id = tracker_metadata_new["max_obj_id"] + inference_session.obj_ids = list(tracker_metadata_new["obj_ids"]) + + inference_session.obj_first_frame_idx = extra_metadata["obj_first_frame_idx"] + inference_session.unmatched_frame_inds = extra_metadata["unmatched_frame_inds"] + inference_session.trk_keep_alive = extra_metadata["trk_keep_alive"] + inference_session.overlap_pair_to_frame_inds = extra_metadata["overlap_pair_to_frame_inds"] + inference_session.removed_obj_ids = removed_obj_ids + inference_session.suppressed_obj_ids[frame_idx] = extra_metadata["suppressed_obj_ids"][frame_idx] + + return Sam3VideoSegmentationOutput( + object_ids=list(tracker_metadata_new["obj_ids"]), + obj_id_to_mask=obj_id_to_mask, + obj_id_to_score=obj_id_to_score, + obj_id_to_tracker_score=tracker_metadata_new["obj_id_to_tracker_score_frame_wise"][frame_idx], + removed_obj_ids=removed_obj_ids, + suppressed_obj_ids=extra_metadata["suppressed_obj_ids"][frame_idx], + frame_idx=frame_idx, + ) + + def _get_processing_order( + self, + inference_session: Sam3VideoInferenceSession, + start_frame_idx: int, + max_frame_num_to_track: int | None = None, + reverse: bool = False, + ): + num_frames = inference_session.num_frames + if max_frame_num_to_track is None: + # default: track all the frames in the video + max_frame_num_to_track = num_frames + if reverse: + end_frame_idx = start_frame_idx - max_frame_num_to_track + end_frame_idx = max(end_frame_idx, 0) + processing_order = range(start_frame_idx - 1, end_frame_idx - 1, -1) + else: + end_frame_idx = start_frame_idx + max_frame_num_to_track + end_frame_idx = min(end_frame_idx, num_frames - 1) + processing_order = range(start_frame_idx, end_frame_idx + 1) + return processing_order, end_frame_idx + + @torch.inference_mode() + @auto_docstring( + custom_intro=""" + Propagate the prompts to get grounding results for the entire video. Used when initializing an inference session with a whole video. + Yields Sam3VideoSegmentationOutput for each frame. + """ + ) + def propagate_in_video_iterator( + self, + inference_session: Sam3VideoInferenceSession, + start_frame_idx: int = 0, + max_frame_num_to_track: int | None = None, + reverse: bool = False, + show_progress_bar: bool = False, + ) -> Iterator[Sam3VideoSegmentationOutput]: + r""" + inference_session (`Sam3VideoInferenceSession`): + The video inference session object. + start_frame_idx (`int`, *optional*, defaults to `0`): + The starting frame index for propagation. + max_frame_num_to_track (`int`, *optional*): + The maximum number of frames to track. If not provided, all frames in the video will be tracked. + reverse (`bool`, *optional*, defaults to `False`): + Whether to propagate in reverse. + show_progress_bar (`bool`, *optional*, defaults to `False`): + Whether to show a progress bar during propagation. + """ + processing_order, end_frame_idx = self._get_processing_order( + inference_session, + start_frame_idx, + max_frame_num_to_track, + reverse=reverse, + ) + + hotstart_buffer = [] + for frame_idx in tqdm(processing_order, desc="propagate in video", disable=not show_progress_bar): + out = self(inference_session=inference_session, frame_idx=frame_idx, reverse=reverse) + + if self.hotstart_delay > 0: + # accumulate the outputs for the first `hotstart_delay` frames + hotstart_buffer.append(out) + # update the object IDs removed by hotstart so that we don't output them + inference_session.hotstart_removed_obj_ids.update(out.removed_obj_ids) + + if frame_idx == end_frame_idx: + # we reached the end of propagation -- yield all frames in the buffer + yield_list = hotstart_buffer + hotstart_buffer = [] + elif len(hotstart_buffer) >= self.hotstart_delay: + # we have enough frames -- yield and remove the first (oldest) frame from the buffer + yield_list = hotstart_buffer[:1] + hotstart_buffer = hotstart_buffer[1:] + else: + # not enough frames yet -- skip yielding + yield_list = [] + else: + yield_list = [out] # output the current frame + + yield from yield_list + + +@torch.jit.script +def fast_diag_box_iou(boxes1, boxes2): + box1_xy = boxes1[:, 2:] + box1_XY = boxes1[:, :2] + box2_xy = boxes2[:, 2:] + box2_XY = boxes2[:, :2] + area1 = (box1_xy - box1_XY).prod(-1) + area2 = (box2_xy - box2_XY).prod(-1) + + lt = torch.max(box1_XY, box2_XY) + rb = torch.min(box1_xy, box2_xy) + + inter = (rb - lt).clamp(min=0).prod(-1) + union = area1 + area2 - inter + iou = inter / union + return iou + + +def mask_iou(pred_masks: torch.Tensor, gt_masks: torch.Tensor) -> torch.Tensor: + """ + Compute the IoU (Intersection over Union) between predicted masks and ground truth masks. + Args: + - pred_masks: (N, H, W) bool Tensor, containing binary predicted segmentation masks + - gt_masks: (M, H, W) bool Tensor, containing binary ground truth segmentation masks + Returns: + - ious: (N, M) float Tensor, containing IoUs for each pair of predicted and ground truth masks + """ + N, H, W = pred_masks.shape + M, _, _ = gt_masks.shape + + # Flatten masks: (N, 1, H*W) and (1, M, H*W) + pred_flat = pred_masks.view(N, 1, H * W) + gt_flat = gt_masks.view(1, M, H * W) + + # Compute intersection and union: (N, M) + intersection = (pred_flat & gt_flat).sum(dim=2).float() + union = (pred_flat | gt_flat).sum(dim=2).float() + ious = intersection / union.clamp(min=1) + return ious # shape: (N, M) + + +def nms_masks( + pred_probs: torch.Tensor, + pred_masks: torch.Tensor, + prob_threshold: float, + iou_threshold: float, +) -> torch.Tensor: + """ + Args: + - pred_probs: (num_det,) float Tensor, containing the score (probability) of each detection + - pred_masks: (num_det, H_mask, W_mask) float Tensor, containing the binary segmentation mask of each detection + - prob_threshold: float, score threshold to prefilter detections (NMS is performed on detections above threshold) + - iou_threshold: float, mask IoU threshold for NMS + + Returns: + - keep: (num_det,) bool Tensor, indicating whether each detection is kept after score thresholding + NMS + """ + # prefilter the detections with prob_threshold ("valid" are those above prob_threshold) + is_valid = pred_probs > prob_threshold # (num_det,) + probs = pred_probs[is_valid] # (num_valid,) + masks_binary = pred_masks[is_valid] > 0 # (num_valid, H_mask, W_mask) + if probs.numel() == 0: + return is_valid # no valid detection, return empty keep mask + + ious = mask_iou(masks_binary, masks_binary) # (num_valid, num_valid) + + # Try to use kernels for NMS, fallback to keeping all valid detections if unavailable + _load_cv_utils_kernel_once() + if not cv_utils_kernel: + return is_valid # Fallback: keep all valid detections without NMS + + try: + kept_inds = cv_utils_kernel.generic_nms(ious, probs, iou_threshold, use_iou_matrix=True) + except Exception as e: + logger.warning_once(f"Failed to run NMS using kernels library: {e}. NMS post-processing will be skipped.") + return is_valid # Fallback: keep all valid detections without NMS + + # valid_inds are the indices among `probs` of valid detections before NMS (or -1 for invalid) + valid_inds = torch.where(is_valid, is_valid.cumsum(dim=0) - 1, -1) # (num_det,) + keep = torch.isin(valid_inds, kept_inds) # (num_det,) + return keep + + +def fill_holes_in_mask_scores(mask, max_area, fill_holes=True, remove_sprinkles=True): + """ + A post processor to fill small holes in mask scores with area under `max_area`. + Holes are those small connected components in either background or foreground. + + Note that it relies on the "cc_torch" package to find connected components fast. You can + install it via the following command (`TORCH_CUDA_ARCH_LIST=8.0` is for A100 GPUs): + ``` + pip uninstall -y cc_torch; TORCH_CUDA_ARCH_LIST=8.0 9.0 pip install git+https://github.com/ronghanghu/cc_torch + ``` + Otherwise, it will fallback to a slightly slower triton implementation, or skimage if the tensor is on cpu + """ + + if max_area <= 0: + return mask # nothing to fill in this case + + if fill_holes: + # We remove small connected components in background by changing them to foreground + # with a small positive mask score (0.1). + mask_bg = mask <= 0 + bg_area_thresh = max_area + _, areas_bg = _get_connected_components_with_padding(mask_bg) + small_components_bg = mask_bg & (areas_bg <= bg_area_thresh) + mask = torch.where(small_components_bg, 0.1, mask) + + if remove_sprinkles: + # We remove small connected components in foreground by changing them to background + # with a small negative mask score (-0.1). Here we only remove connected components + # whose areas are under both `max_area` and half of the entire mask's area. This + # removes sprinkles while avoids filtering out tiny objects that we want to track. + mask_fg = mask > 0 + fg_area_thresh = torch.sum(mask_fg, dim=(2, 3), keepdim=True, dtype=torch.int32) + fg_area_thresh.floor_divide_(2).clamp_(max=max_area) + _, areas_fg = _get_connected_components_with_padding(mask_fg) + small_components_fg = mask_fg & (areas_fg <= fg_area_thresh) + mask = torch.where(small_components_fg, -0.1, mask) + return mask + + +def _get_connected_components_with_padding(mask): + """Get connected components from masks (possibly padding them to an even size).""" + mask = mask.to(torch.uint8) + _, _, H, W = mask.shape + + # Try to use kernels for connected components, fallback if unavailable + _load_cv_utils_kernel_once() + if not cv_utils_kernel: + # Fallback: return dummy labels and counts that won't trigger filtering + labels = torch.zeros_like(mask, dtype=torch.int32) + counts = torch.full_like(mask, fill_value=mask.shape[2] * mask.shape[3] + 1, dtype=torch.int32) + return labels, counts + + # make sure both height and width are even (to be compatible with cc_torch) + pad_h = H % 2 + pad_w = W % 2 + + try: + if pad_h == 0 and pad_w == 0: + labels, counts = cv_utils_kernel.cc_2d(mask.contiguous(), get_counts=True) + else: + # pad the mask to make its height and width even + # padding format is (padding_left,padding_right,padding_top,padding_bottom) + mask_pad = F.pad(mask, (0, pad_w, 0, pad_h), mode="constant", value=0) + labels, counts = cv_utils_kernel.cc_2d(mask_pad.contiguous(), get_counts=True) + labels = labels[:, :, :H, :W] + counts = counts[:, :, :H, :W] + except Exception as e: + logger.warning_once( + f"Failed to compute connected components using kernels library: {e}. " + "Hole filling and sprinkle removal will be skipped." + ) + # Fallback: return dummy labels and counts that won't trigger filtering + labels = torch.zeros_like(mask, dtype=torch.int32) + counts = torch.full_like(mask, fill_value=H * W + 1, dtype=torch.int32) + return labels, counts + + return labels, counts + + +__all__ = [ + "Sam3VideoModel", + "Sam3VideoPreTrainedModel", + "Sam3VideoInferenceSession", + "Sam3VideoSegmentationOutput", +] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam3_video/processing_sam3_video.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam3_video/processing_sam3_video.py new file mode 100644 index 0000000000000000000000000000000000000000..1a93f3f322bee3b1c72b596a7c9ff38c99ca94db --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam3_video/processing_sam3_video.py @@ -0,0 +1,365 @@ +# Copyright 2025 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from typing import Union + +import torch +from torchvision.ops import masks_to_boxes + +from ...image_utils import ImageInput +from ...processing_utils import ProcessorMixin +from ...tokenization_utils_base import BatchEncoding +from ...utils import TensorType, auto_docstring +from ...utils.import_utils import requires +from ...video_utils import VideoInput +from .modeling_sam3_video import Sam3VideoInferenceSession + + +@requires(backends=("torch",)) +@auto_docstring +class Sam3VideoProcessor(ProcessorMixin): + def __init__( + self, + image_processor, + video_processor, + tokenizer, + target_size: int | None = None, + **kwargs, + ): + r""" + target_size (`int`, *optional*): + The target size (target_size, target_size) to which the image will be resized. + """ + super().__init__(image_processor, video_processor, tokenizer, **kwargs) + self.target_size = target_size if target_size is not None else self.image_processor.size["height"] + + @auto_docstring + def __call__( + self, + images: ImageInput | None = None, + segmentation_maps: ImageInput | None = None, + original_sizes: list[list[float]] | torch.Tensor | None = None, + return_tensors: str | TensorType | None = None, + **kwargs, + ) -> BatchEncoding: + r""" + images (`ImageInput`, *optional*): + The image(s) to process. + segmentation_maps (`ImageInput`, *optional*): + The segmentation maps to process (optional, for image processor). + original_sizes (`list[list[float]]`, `torch.Tensor`, *optional*): + The original sizes of the images. Only used when images is not provided. + + Returns: + A [`BatchEncoding`] with the following fields: + - `pixel_values` (`torch.Tensor`): The processed image(s). + - `original_sizes` (`list[list[float]]`): The original sizes of the images. + - `labels` (`torch.Tensor`, *optional*): The processed segmentation maps (if provided). + """ + if images is not None: + encoding_image_processor = self.image_processor( + images, + segmentation_maps=segmentation_maps, + return_tensors=return_tensors, + **kwargs, + ) + elif original_sizes is not None: + if isinstance(original_sizes, torch.Tensor): + original_sizes = original_sizes.cpu().tolist() + encoding_image_processor = BatchEncoding({"original_sizes": original_sizes}, tensor_type=return_tensors) + else: + raise ValueError("Either images or original_sizes must be provided") + + original_sizes = encoding_image_processor["original_sizes"] + # Check original_sizes is of length 1 or len(images) + if images is not None and len(original_sizes) != 1 and len(original_sizes) != len(images): + raise ValueError( + "original_sizes must be of length 1 or len(images). If you are passing a single image, you must pass a single original_size." + ) + + return encoding_image_processor + + def add_text_prompt(self, inference_session: Sam3VideoInferenceSession, text: str | list[str]): + """ + Add text prompt(s) to the inference session. + + Args: + inference_session (`Sam3VideoInferenceSession`): The inference session. + text (`str` or `list[str]`): The text prompt(s) to add. + + Returns: + `Sam3VideoInferenceSession`: The inference session with the added text prompt(s). + """ + if isinstance(text, str): + text = [text] + + prompt_ids = [] + for prompt_text in text: + # Add prompt and get its ID (reuses existing if duplicate) + prompt_id = inference_session.add_prompt(prompt_text) + + # Only encode if this is a new prompt (not already in prompt_input_ids) + if prompt_id not in inference_session.prompt_input_ids: + encoded_text = self.tokenizer( + prompt_text, return_tensors="pt", padding="max_length", max_length=32 + ).to(inference_session.inference_device) + + inference_session.prompt_input_ids[prompt_id] = encoded_text.input_ids + inference_session.prompt_attention_masks[prompt_id] = encoded_text.attention_mask + + prompt_ids.append(prompt_id) + + return inference_session + + def init_video_session( + self, + video: VideoInput | None = None, + inference_device: Union[str, "torch.device"] = "cpu", + inference_state_device: Union[str, "torch.device"] | None = None, + processing_device: Union[str, "torch.device"] | None = None, + video_storage_device: Union[str, "torch.device"] | None = None, + max_vision_features_cache_size: int = 1, + dtype: torch.dtype = torch.float32, + ): + """ + Initializes a video session for inference. + If a video is provided (async inference), the video will be processed and stored on the `video_storage_device`. + + Args: + video (`VideoInput`, *optional*): + The video to process. No need to provide when streaming. + inference_device (`str` or `torch.device`, *optional*, defaults to "cpu"): + The device to use for inference. + inference_state_device (`str` or `torch.device`, *optional*): + The device to store the inference state on. + processing_device (`str` or `torch.device`, *optional*): + The device to use for video processing. + video_storage_device (`str` or `torch.device`, *optional*): + The device to store the processed video frames on. + max_vision_features_cache_size (`int`, *optional*, defaults to 1): + The maximum number of vision features to cache. + dtype (`torch.dtype`, *optional*, defaults to `torch.float32`): + The torch dtype to use for the whole session. + """ + video_storage_device = video_storage_device if video_storage_device is not None else inference_device + inference_state_device = inference_state_device if inference_state_device is not None else inference_device + processing_device = processing_device if processing_device is not None else inference_device + pixel_values_video = None + video_height = None + video_width = None + if video is not None: + processed_video = self.video_processor(videos=video, device=processing_device, return_tensors="pt") + pixel_values_video = processed_video.pixel_values_videos[0] + video_height = processed_video.original_sizes[0][0] + video_width = processed_video.original_sizes[0][1] + inference_session = Sam3VideoInferenceSession( + video=pixel_values_video, + video_height=video_height, + video_width=video_width, + inference_device=inference_device, + video_storage_device=video_storage_device, + inference_state_device=inference_state_device, + dtype=dtype, + max_vision_features_cache_size=max_vision_features_cache_size, + ) + return inference_session + + def _apply_non_overlapping_constraints(self, pred_masks): + """ + Apply non-overlapping constraints to the object scores in pred_masks. Here we + keep only the highest scoring object at each spatial location in pred_masks. + """ + batch_size = pred_masks.size(0) + if batch_size == 1: + return pred_masks + + device = pred_masks.device + # "max_obj_inds": object index of the object with the highest score at each location + max_obj_inds = torch.argmax(pred_masks, dim=0, keepdim=True) + # "batch_obj_inds": object index of each object slice (along dim 0) in `pred_masks` + batch_obj_inds = torch.arange(batch_size, device=device)[:, None, None, None] + keep = max_obj_inds == batch_obj_inds + # suppress overlapping regions' scores below -10.0 so that the foreground regions + # don't overlap (here sigmoid(-10.0)=4.5398e-05) + pred_masks = torch.where(keep, pred_masks, torch.clamp(pred_masks, max=-10.0)) + return pred_masks + + def _apply_object_wise_non_overlapping_constraints( + self, + pred_masks, + obj_scores, + background_value=-10.0, + prompt_ids=None, + ): + """ + Applies non-overlapping constraints object wise (i.e. only one object can claim the overlapping region). + Constraints are enforced independently for each prompt group when `prompt_ids` are provided. + """ + if prompt_ids is None: + return self._apply_object_wise_non_overlapping_constraints_impl(pred_masks, obj_scores, background_value) + + if len(prompt_ids) != pred_masks.size(0): + raise ValueError("prompt_ids must have the same length as pred_masks") + + pred_masks_grouped = pred_masks.clone() + prompt_ids_tensor = torch.tensor(prompt_ids, device=pred_masks.device, dtype=torch.long) + for prompt_id in prompt_ids_tensor.unique(sorted=True): + indices = torch.nonzero(prompt_ids_tensor == prompt_id, as_tuple=True)[0] + if indices.numel() == 0: + continue + prompt_masks = self._apply_object_wise_non_overlapping_constraints_impl( + pred_masks_grouped[indices], + obj_scores[indices], + background_value, + ) + pred_masks_grouped[indices] = prompt_masks.to(pred_masks_grouped.dtype) + return pred_masks_grouped + + def _apply_object_wise_non_overlapping_constraints_impl(self, pred_masks, obj_scores, background_value=-10.0): + pred_masks_single_score = torch.where(pred_masks > 0, obj_scores[..., None, None], background_value) + pixel_level_non_overlapping_masks = self._apply_non_overlapping_constraints(pred_masks_single_score) + pred_masks = torch.where( + pixel_level_non_overlapping_masks > 0, + pred_masks, + torch.clamp(pred_masks, max=background_value), + ) + return pred_masks.to(pred_masks_single_score.dtype) + + def postprocess_outputs( + self, + inference_session, + model_outputs, + original_sizes: list[list[float]] | torch.Tensor | None = None, + ): + """ + Post-process model outputs to get final masks, boxes, and scores. + + Args: + inference_session (`Sam3VideoInferenceSession`): + The inference session object. + model_outputs (`Sam3VideoSegmentationOutput`): + The raw model output from `Sam3VideoModel.forward()`. + original_sizes (`list[list[float]]` or `torch.Tensor`, *optional*): + Optional original frame sizes [height, width]. Required for streaming inference + when video_height/video_width are not set in the session. + + Returns: + `dict`: A dictionary containing the following keys: + - **object_ids** (`torch.Tensor` of shape `(num_objects,)`): Object IDs for each detected object. + - **scores** (`torch.Tensor` of shape `(num_objects,)`): Detection scores for each object. + - **boxes** (`torch.Tensor` of shape `(num_objects, 4)`): Bounding boxes in XYXY format + (top_left_x, top_left_y, bottom_right_x, bottom_right_y). + - **masks** (`torch.Tensor` of shape `(num_objects, height, width)`): Binary segmentation masks + for each object at the original video resolution. + - **prompt_to_obj_ids** (`dict[str, list[int]]`): Mapping from prompt text to list of + object IDs detected by that prompt. + """ + obj_id_to_mask = model_outputs["obj_id_to_mask"] # low res masks (1, H_low, W_low) + curr_obj_ids = sorted(obj_id_to_mask.keys()) + + # Get video dimensions - use original_sizes for streaming inference if session doesn't have them + if inference_session.video_height is not None and inference_session.video_width is not None: + H_video, W_video = inference_session.video_height, inference_session.video_width + elif original_sizes is not None: + if isinstance(original_sizes, torch.Tensor): + original_sizes = original_sizes.cpu().tolist() + # original_sizes is a list of [height, width] pairs, take the first one + if isinstance(original_sizes[0], list): + H_video, W_video = int(original_sizes[0][0]), int(original_sizes[0][1]) + else: + H_video, W_video = int(original_sizes[0]), int(original_sizes[1]) + else: + raise ValueError( + "Either inference_session.video_height/video_width must be set, " + "or original_sizes must be provided for streaming inference." + ) + if len(curr_obj_ids) == 0: + out_obj_ids = torch.zeros(0, dtype=torch.int64) + out_probs = torch.zeros(0, dtype=torch.float32) + out_binary_masks = torch.zeros(0, H_video, W_video, dtype=torch.bool) + out_boxes_xyxy = torch.zeros(0, 4, dtype=torch.float32) + else: + out_obj_ids = torch.tensor(curr_obj_ids, dtype=torch.int64) + out_probs = torch.tensor([model_outputs["obj_id_to_score"][obj_id] for obj_id in curr_obj_ids]) + out_tracker_probs = torch.tensor( + [model_outputs["obj_id_to_tracker_score"].get(obj_id, 0.0) for obj_id in curr_obj_ids] + ) + + # Interpolate low-res masks to video resolution + low_res_masks = torch.cat([obj_id_to_mask[obj_id] for obj_id in curr_obj_ids], dim=0) # (N, H_low, W_low) + # Add channel dimension for interpolation: (N, H, W) -> (N, 1, H, W) + out_binary_masks = torch.nn.functional.interpolate( + low_res_masks.unsqueeze(1), + size=(H_video, W_video), + mode="bilinear", + align_corners=False, + ).squeeze(1) # (N, H_video, W_video) + out_binary_masks = out_binary_masks > 0 + + assert out_binary_masks.dtype == torch.bool + keep = out_binary_masks.any(dim=(1, 2)).cpu() # remove masks with 0 areas + # hide outputs for those object IDs in `obj_ids_to_hide` + obj_ids_to_hide = [] + if model_outputs["suppressed_obj_ids"] is not None: + obj_ids_to_hide.extend(list(model_outputs["suppressed_obj_ids"])) + if len(inference_session.hotstart_removed_obj_ids) > 0: + obj_ids_to_hide.extend(list(inference_session.hotstart_removed_obj_ids)) + if len(obj_ids_to_hide) > 0: + obj_ids_to_hide_t = torch.tensor(obj_ids_to_hide, dtype=torch.int64) + keep &= ~torch.isin(out_obj_ids, obj_ids_to_hide_t) + + # slice those valid entries from the original outputs + keep_idx = torch.nonzero(keep, as_tuple=True)[0] + keep_idx_gpu = keep_idx.to(device=out_binary_masks.device, non_blocking=True) + + out_obj_ids = torch.index_select(out_obj_ids, 0, keep_idx) + out_probs = torch.index_select(out_probs, 0, keep_idx) + out_tracker_probs = torch.index_select(out_tracker_probs, 0, keep_idx) + out_binary_masks = torch.index_select(out_binary_masks, 0, keep_idx_gpu) + + out_boxes_xyxy = masks_to_boxes(out_binary_masks) + + # Apply non-overlapping constraints on the existing masklets. + # Constraints are enforced independently per prompt group. + if out_binary_masks.shape[0] > 1: + assert len(out_binary_masks) == len(out_tracker_probs) + prompt_ids_filtered = [ + inference_session.obj_id_to_prompt_id[int(obj_id)] for obj_id in out_obj_ids.tolist() + ] + out_binary_masks = ( + self._apply_object_wise_non_overlapping_constraints( + out_binary_masks.unsqueeze(1), + out_tracker_probs.unsqueeze(1).to(out_binary_masks.device), + background_value=0, + prompt_ids=prompt_ids_filtered, + ).squeeze(1) + ) > 0 + + # Build prompt_to_obj_ids mapping: group object IDs by their associated prompt text. + prompt_to_obj_ids = {} + for obj_id in out_obj_ids.tolist(): + prompt_id = inference_session.obj_id_to_prompt_id[obj_id] + prompt_text = inference_session.prompts[prompt_id] + prompt_to_obj_ids.setdefault(prompt_text, []).append(obj_id) + + outputs = { + "object_ids": out_obj_ids, + "scores": out_probs, + "boxes": out_boxes_xyxy, + "masks": out_binary_masks, + "prompt_to_obj_ids": prompt_to_obj_ids, + } + return outputs + + +__all__ = ["Sam3VideoProcessor"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam_hq/__init__.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam_hq/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..f56ba4c932c5fc6a011cb876a48964f2322ef1b7 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam_hq/__init__.py @@ -0,0 +1,28 @@ +# Copyright 2025 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from typing import TYPE_CHECKING + +from ...utils import _LazyModule +from ...utils.import_utils import define_import_structure + + +if TYPE_CHECKING: + from .configuration_sam_hq import * + from .modeling_sam_hq import * + from .processing_sam_hq import * +else: + import sys + + _file = globals()["__file__"] + sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__) diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam_hq/configuration_sam_hq.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam_hq/configuration_sam_hq.py new file mode 100644 index 0000000000000000000000000000000000000000..b11b0744dd4886e8e053fbb736e1807977dec890 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam_hq/configuration_sam_hq.py @@ -0,0 +1,315 @@ +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# This file was automatically generated from src/transformers/models/sam_hq/modular_sam_hq.py. +# Do NOT edit this file manually as any edits will be overwritten by the generation of +# the file from the modular. If any change should be done, please apply the change to the +# modular_sam_hq.py file directly. One of our CI enforces this. +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# Copyright 2025 Google Inc. HuggingFace Inc. team. All rights reserved. +# +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +from ...configuration_utils import PreTrainedConfig + + +class SamHQPromptEncoderConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`SamHQPromptEncoderModel`].The [`SamHQPromptEncoderModel`] + module is used to encode the input 2D points and bounding boxes. Instantiating a configuration defaults will yield a + similar configuration to that of the SAM_HQ model. The configuration is used to store the configuration of the model. + [Uminosachi/sam-hq](https://huggingface.co/Uminosachi/sam-hq) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model's output.Read the documentation from + [`PreTrainedConfig`] for more information. + + Args: + hidden_size (`int`, *optional*, defaults to 256): + Dimensionality of the hidden states. + image_size (`int`, *optional*, defaults to 1024): + The expected output resolution of the image. + patch_size (`int`, *optional*, defaults to 16): + The size (resolution) of each patch. + mask_input_channels (`int`, *optional*, defaults to 16): + The number of channels to be fed to the `MaskDecoder` module. + num_point_embeddings (`int`, *optional*, defaults to 4): + The number of point embeddings to be used. + hidden_act (`str`, *optional*, defaults to `"gelu"`): + The non-linear activation function in the encoder and pooler. + """ + + base_config_key = "prompt_encoder_config" + + def __init__( + self, + hidden_size=256, + image_size=1024, + patch_size=16, + mask_input_channels=16, + num_point_embeddings=4, + hidden_act="gelu", + layer_norm_eps=1e-6, + **kwargs, + ): + super().__init__(**kwargs) + self.hidden_size = hidden_size + self.image_size = image_size + self.patch_size = patch_size + self.image_embedding_size = image_size // patch_size + self.mask_input_channels = mask_input_channels + self.num_point_embeddings = num_point_embeddings + self.hidden_act = hidden_act + self.layer_norm_eps = layer_norm_eps + + +class SamHQVisionConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`SamHQVisionModel`]. It is used to instantiate a SAM_HQ + vision encoder according to the specified arguments, defining the model architecture. Instantiating a configuration + defaults will yield a similar configuration to that of the SAM_HQ ViT-h + [facebook/sam_hq-vit-huge](https://huggingface.co/facebook/sam_hq-vit-huge) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + hidden_size (`int`, *optional*, defaults to 768): + Dimensionality of the encoder layers and the pooler layer. + output_channels (`int`, *optional*, defaults to 256): + Dimensionality of the output channels in the Patch Encoder. + num_hidden_layers (`int`, *optional*, defaults to 12): + Number of hidden layers in the Transformer encoder. + num_attention_heads (`int`, *optional*, defaults to 12): + Number of attention heads for each attention layer in the Transformer encoder. + num_channels (`int`, *optional*, defaults to 3): + Number of channels in the input image. + image_size (`int`, *optional*, defaults to 1024): + Expected resolution. Target size of the resized input image. + patch_size (`int`, *optional*, defaults to 16): + Size of the patches to be extracted from the input image. + hidden_act (`str`, *optional*, defaults to `"gelu"`): + The non-linear activation function (function or string) + layer_norm_eps (`float`, *optional*, defaults to 1e-06): + The epsilon used by the layer normalization layers. + attention_dropout (`float`, *optional*, defaults to 0.0): + The dropout ratio for the attention probabilities. + initializer_range (`float`, *optional*, defaults to 1e-10): + The standard deviation of the truncated_normal_initializer for initializing all weight matrices. + qkv_bias (`bool`, *optional*, defaults to `True`): + Whether to add a bias to query, key, value projections. + mlp_ratio (`float`, *optional*, defaults to 4.0): + Ratio of mlp hidden dim to embedding dim. + use_abs_pos (`bool`, *optional*, defaults to `True`): + Whether to use absolute position embedding. + use_rel_pos (`bool`, *optional*, defaults to `True`): + Whether to use relative position embedding. + window_size (`int`, *optional*, defaults to 14): + Window size for relative position. + global_attn_indexes (`list[int]`, *optional*, defaults to `[2, 5, 8, 11]`): + The indexes of the global attention layers. + num_pos_feats (`int`, *optional*, defaults to 128): + The dimensionality of the position embedding. + mlp_dim (`int`, *optional*): + The dimensionality of the MLP layer in the Transformer encoder. If `None`, defaults to `mlp_ratio * + hidden_size`. + + Example: + + ```python + >>> from transformers import ( + ... SamHQVisionConfig, + ... SamHQVisionModel, + ... ) + + >>> # Initializing a SamHQVisionConfig with `"facebook/sam_hq-vit-huge"` style configuration + >>> configuration = SamHQVisionConfig() + + >>> # Initializing a SamHQVisionModel (with random weights) from the `"facebook/sam_hq-vit-huge"` style configuration + >>> model = SamHQVisionModel(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + base_config_key = "vision_config" + model_type = "sam_hq_vision_model" + + def __init__( + self, + hidden_size=768, + output_channels=256, + num_hidden_layers=12, + num_attention_heads=12, + num_channels=3, + image_size=1024, + patch_size=16, + hidden_act="gelu", + layer_norm_eps=1e-06, + attention_dropout=0.0, + initializer_range=1e-10, + qkv_bias=True, + mlp_ratio=4.0, + use_abs_pos=True, + use_rel_pos=True, + window_size=14, + global_attn_indexes=[2, 5, 8, 11], + num_pos_feats=128, + mlp_dim=None, + **kwargs, + ): + super().__init__(**kwargs) + + self.hidden_size = hidden_size + self.output_channels = output_channels + self.num_hidden_layers = num_hidden_layers + self.num_attention_heads = num_attention_heads + self.num_channels = num_channels + self.image_size = image_size + self.patch_size = patch_size + self.hidden_act = hidden_act + self.layer_norm_eps = layer_norm_eps + self.attention_dropout = attention_dropout + self.initializer_range = initializer_range + self.qkv_bias = qkv_bias + self.mlp_ratio = mlp_ratio + self.use_abs_pos = use_abs_pos + self.use_rel_pos = use_rel_pos + self.window_size = window_size + self.global_attn_indexes = global_attn_indexes + self.num_pos_feats = num_pos_feats + self.mlp_dim = int(hidden_size * mlp_ratio) if mlp_dim is None else mlp_dim + self.scale = self.hidden_size // 2 + + +class SamHQMaskDecoderConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`SamHQMaskDecoder`]. It is used to instantiate a SAM_HQ + mask decoder to the specified arguments, defining the model architecture. Instantiating a configuration defaults + will yield a similar configuration to that of the SAM_HQ-vit-h + [facebook/sam_hq-vit-huge](https://huggingface.co/facebook/sam_hq-vit-huge) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + hidden_size (`int`, *optional*, defaults to 256): + Dimensionality of the hidden states. + hidden_act (`str`, *optional*, defaults to `"relu"`): + The non-linear activation function used inside the `SamHQMaskDecoder` module. + mlp_dim (`int`, *optional*, defaults to 2048): + Dimensionality of the "intermediate" (i.e., feed-forward) layer in the Transformer encoder. + num_hidden_layers (`int`, *optional*, defaults to 2): + Number of hidden layers in the Transformer encoder. + num_attention_heads (`int`, *optional*, defaults to 8): + Number of attention heads for each attention layer in the Transformer encoder. + attention_downsample_rate (`int`, *optional*, defaults to 2): + The downsampling rate of the attention layer. + num_multimask_outputs (`int`, *optional*, defaults to 3): + The number of outputs from the `SamHQMaskDecoder` module. In the Segment Anything paper, this is set to 3. + iou_head_depth (`int`, *optional*, defaults to 3): + The number of layers in the IoU head module. + iou_head_hidden_dim (`int`, *optional*, defaults to 256): + The dimensionality of the hidden states in the IoU head module. + layer_norm_eps (`float`, *optional*, defaults to 1e-06): + The epsilon used by the layer normalization layers. + vit_dim (`int`, *optional*, defaults to 768): + Dimensionality of the Vision Transformer (ViT) used in the `SamHQMaskDecoder` module. + """ + + base_config_key = "mask_decoder_config" + + def __init__( + self, + hidden_size=256, + hidden_act="relu", + mlp_dim=2048, + num_hidden_layers=2, + num_attention_heads=8, + attention_downsample_rate=2, + num_multimask_outputs=3, + iou_head_depth=3, + iou_head_hidden_dim=256, + layer_norm_eps=1e-6, + vit_dim=768, + **kwargs, + ): + super().__init__(**kwargs) + self.hidden_size = hidden_size + self.hidden_act = hidden_act + self.mlp_dim = mlp_dim + self.num_hidden_layers = num_hidden_layers + self.num_attention_heads = num_attention_heads + self.attention_downsample_rate = attention_downsample_rate + self.num_multimask_outputs = num_multimask_outputs + self.iou_head_depth = iou_head_depth + self.iou_head_hidden_dim = iou_head_hidden_dim + self.layer_norm_eps = layer_norm_eps + self.vit_dim = vit_dim + + +class SamHQConfig(PreTrainedConfig): + r""" + [`SamHQConfig`] is the configuration class to store the configuration of a [`SamHQModel`]. It is used to instantiate a + SAM-HQ model according to the specified arguments, defining the vision model, prompt-encoder model and mask decoder + configs. Instantiating a configuration with the defaults will yield a similar configuration to that of the + SAM-HQ-ViT-H [sushmanth/sam_hq_vit_h](https://huggingface.co/sushmanth/sam_hq_vit_h) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + vision_config (Union[`dict`, `SamHQVisionConfig`], *optional*): + Dictionary of configuration options used to initialize [`SamHQVisionConfig`]. + prompt_encoder_config (Union[`dict`, `SamHQPromptEncoderConfig`], *optional*): + Dictionary of configuration options used to initialize [`SamHQPromptEncoderConfig`]. + mask_decoder_config (Union[`dict`, `SamHQMaskDecoderConfig`], *optional*): + Dictionary of configuration options used to initialize [`SamHQMaskDecoderConfig`]. + kwargs (*optional*): + Dictionary of keyword arguments. + """ + + model_type = "sam_hq" + sub_configs = { + "prompt_encoder_config": SamHQPromptEncoderConfig, + "mask_decoder_config": SamHQMaskDecoderConfig, + "vision_config": SamHQVisionConfig, + } + + def __init__( + self, + vision_config=None, + prompt_encoder_config=None, + mask_decoder_config=None, + initializer_range=0.02, + tie_word_embeddings=True, + **kwargs, + ): + vision_config = vision_config if vision_config is not None else {} + prompt_encoder_config = prompt_encoder_config if prompt_encoder_config is not None else {} + mask_decoder_config = mask_decoder_config if mask_decoder_config is not None else {} + + if isinstance(vision_config, SamHQVisionConfig): + vision_config = vision_config.to_dict() + if isinstance(prompt_encoder_config, SamHQPromptEncoderConfig): + prompt_encoder_config = prompt_encoder_config.to_dict() + if isinstance(mask_decoder_config, SamHQMaskDecoderConfig): + mask_decoder_config = mask_decoder_config.to_dict() + + self.vision_config = SamHQVisionConfig(**vision_config) + self.prompt_encoder_config = SamHQPromptEncoderConfig(**prompt_encoder_config) + self.mask_decoder_config = SamHQMaskDecoderConfig(**mask_decoder_config) + self.initializer_range = initializer_range + self.tie_word_embeddings = tie_word_embeddings + super().__init__(**kwargs) + + +__all__ = ["SamHQVisionConfig", "SamHQMaskDecoderConfig", "SamHQPromptEncoderConfig", "SamHQConfig"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam_hq/modeling_sam_hq.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam_hq/modeling_sam_hq.py new file mode 100644 index 0000000000000000000000000000000000000000..83e558989b69e8dbdd697a5217c89028c78389ab --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam_hq/modeling_sam_hq.py @@ -0,0 +1,1490 @@ +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# This file was automatically generated from src/transformers/models/sam_hq/modular_sam_hq.py. +# Do NOT edit this file manually as any edits will be overwritten by the generation of +# the file from the modular. If any change should be done, please apply the change to the +# modular_sam_hq.py file directly. One of our CI enforces this. +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# Copyright 2025 Google Inc. HuggingFace Inc. team. All rights reserved. +# +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +import collections +from collections.abc import Callable +from dataclasses import dataclass + +import numpy as np +import torch +import torch.nn.functional as F +from torch import Tensor, nn + +from ... import initialization as init +from ...activations import ACT2FN +from ...modeling_layers import GradientCheckpointingLayer +from ...modeling_outputs import BaseModelOutput +from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel +from ...processing_utils import Unpack +from ...utils import auto_docstring, logging +from ...utils.generic import ModelOutput, TransformersKwargs, merge_with_config_defaults +from ...utils.output_capturing import OutputRecorder, capture_outputs +from .configuration_sam_hq import SamHQConfig, SamHQMaskDecoderConfig, SamHQPromptEncoderConfig, SamHQVisionConfig + + +logger = logging.get_logger(__name__) + + +@dataclass +@auto_docstring( + custom_intro=""" + Base class for sam_hq vision model's outputs that also contains image embeddings obtained by applying the projection + layer to the pooler_output. + """ +) +class SamHQVisionEncoderOutput(ModelOutput): + r""" + image_embeds (`torch.FloatTensor` of shape `(batch_size, output_dim)` *optional* returned when model is initialized with `with_projection=True`): + The image embeddings obtained by applying the projection layer to the pooler_output. + intermediate_embeddings (`list(torch.FloatTensor)`, *optional*): + A list of intermediate embeddings collected from certain blocks within the model, typically those without + windowed attention. Each element in the list is of shape `(batch_size, sequence_length, hidden_size)`. + This is specific to SAM-HQ and not present in base SAM. + """ + + image_embeds: torch.FloatTensor | None = None + last_hidden_state: torch.FloatTensor | None = None + hidden_states: tuple[torch.FloatTensor, ...] | None = None + attentions: tuple[torch.FloatTensor, ...] | None = None + + intermediate_embeddings: list[torch.FloatTensor] | None = None + + +@dataclass +class SamHQMMaskDecoderOutputs(ModelOutput): + r""" + masks (`torch.FloatTensor` of shape `(batch_size, num_prompts, num_masks, height, width)`): + The predicted masks for the input image. The masks are of shape `(batch_size, num_prompts, num_masks, height, width)`. + iou_scores (`torch.FloatTensor` of shape `(batch_size, num_prompts, num_masks)`): + The predicted IoU scores for each mask. The scores are of shape `(batch_size, num_prompts, num_masks)`. + mask_decoder_attentions (`torch.FloatTensor`, *optional*): + The attention weights from the mask decoder, if `output_attentions=True` was passed during the forward pass. + This is specific to SAM-HQ and not present in base SAM. + """ + + masks: torch.FloatTensor + iou_scores: torch.FloatTensor | None = None + mask_decoder_attentions: torch.FloatTensor | None = None + + +@dataclass +@auto_docstring( + custom_intro=""" + Base class for Segment-Anything model's output + """ +) +class SamHQImageSegmentationOutput(ModelOutput): + r""" + iou_scores (`torch.FloatTensor` of shape `(batch_size, num_masks)`): + The iou scores of the predicted masks. + pred_masks (`torch.FloatTensor` of shape `(batch_size, num_masks, height, width)`): + The predicted low resolutions masks. Needs to be post-processed by the processor + vision_hidden_states (`tuple(torch.FloatTensor)`, *optional*, returned when `output_hidden_states=True` is passed or when `config.output_hidden_states=True`): + Tuple of `torch.FloatTensor` (one for the output of the embeddings, if the model has an embedding layer, + + one for the output of each layer) of shape `(batch_size, sequence_length, hidden_size)`. + + Hidden-states of the vision model at the output of each layer plus the optional initial embedding outputs. + vision_attentions (`tuple(torch.FloatTensor)`, *optional*, returned when `output_attentions=True` is passed or when `config.output_attentions=True`): + Tuple of `torch.FloatTensor` (one for each layer) of shape `(batch_size, num_heads, sequence_length, + sequence_length)`. + + Attentions weights after the attention softmax, used to compute the weighted average in the self-attention + heads. + mask_decoder_attentions (`tuple(torch.FloatTensor)`, *optional*, returned when `output_attentions=True` is passed or when `config.output_attentions=True`): + Tuple of `torch.FloatTensor` (one for each layer) of shape `(batch_size, num_heads, sequence_length, + sequence_length)`. + + Attentions weights after the attention softmax, used to compute the weighted average in the self-attention + heads. + """ + + iou_scores: torch.FloatTensor | None = None + pred_masks: torch.FloatTensor | None = None + vision_hidden_states: tuple[torch.FloatTensor, ...] | None = None + vision_attentions: tuple[torch.FloatTensor, ...] | None = None + mask_decoder_attentions: tuple[torch.FloatTensor, ...] | None = None + + +class SamHQVisionAttention(nn.Module): + """Multi-head Attention block with relative position embeddings.""" + + def __init__(self, config, window_size): + super().__init__() + input_size = ( + (config.image_size // config.patch_size, config.image_size // config.patch_size) + if window_size == 0 + else (window_size, window_size) + ) + + self.num_attention_heads = config.num_attention_heads + head_dim = config.hidden_size // config.num_attention_heads + self.scale = head_dim**-0.5 + self.dropout = config.attention_dropout + + self.qkv = nn.Linear(config.hidden_size, config.hidden_size * 3, bias=config.qkv_bias) + self.proj = nn.Linear(config.hidden_size, config.hidden_size) + + self.use_rel_pos = config.use_rel_pos + if self.use_rel_pos: + if input_size is None: + raise ValueError("Input size must be provided if using relative positional encoding.") + + # initialize relative positional embeddings + self.rel_pos_h = nn.Parameter(torch.zeros(2 * input_size[0] - 1, head_dim)) + self.rel_pos_w = nn.Parameter(torch.zeros(2 * input_size[1] - 1, head_dim)) + + def get_rel_pos(self, q_size: int, k_size: int, rel_pos: torch.Tensor) -> torch.Tensor: + """ + Get relative positional embeddings according to the relative positions of + query and key sizes. + + Args: + q_size (int): + size of the query. + k_size (int): + size of key k. + rel_pos (`torch.Tensor`): + relative position embeddings (L, channel). + + Returns: + Extracted positional embeddings according to relative positions. + """ + max_rel_dist = int(2 * max(q_size, k_size) - 1) + # Interpolate rel pos. + rel_pos_resized = F.interpolate( + rel_pos.reshape(1, rel_pos.shape[0], -1).permute(0, 2, 1), + size=max_rel_dist, + mode="linear", + ) + rel_pos_resized = rel_pos_resized.reshape(-1, max_rel_dist).permute(1, 0) + + # Scale the coords with short length if shapes for q and k are different. + q_coords = torch.arange(q_size)[:, None] * max(k_size / q_size, 1.0) + k_coords = torch.arange(k_size)[None, :] * max(q_size / k_size, 1.0) + relative_coords = (q_coords - k_coords) + (k_size - 1) * max(q_size / k_size, 1.0) + + return rel_pos_resized[relative_coords.long()] + + def get_decomposed_rel_pos( + self, + query: torch.Tensor, + rel_pos_h: torch.Tensor, + rel_pos_w: torch.Tensor, + q_size: tuple[int, int], + k_size: tuple[int, int], + ) -> torch.Tensor: + """ + Calculate decomposed Relative Positional Embeddings from :paper:`mvitv2`. + https://github.com/facebookresearch/mvit/blob/19786631e330df9f3622e5402b4a419a263a2c80/mvit/models/attention.py + + Args: + query (`torch.Tensor`): + query q in the attention layer with shape (batch_size, query_height * query_width, channel). + rel_pos_h (`torch.Tensor`): + relative position embeddings (Lh, channel) for height axis. + rel_pos_w (`torch.Tensor`): + relative position embeddings (Lw, channel) for width axis. + q_size (tuple): + spatial sequence size of query q with (query_height, query_width). + k_size (tuple): + spatial sequence size of key k with (key_height, key_width). + + Returns: + decomposed_rel_pos (`torch.Tensor`): + decomposed relative position embeddings. + """ + query_height, query_width = q_size + key_height, key_width = k_size + relative_position_height = self.get_rel_pos(query_height, key_height, rel_pos_h) + relative_position_width = self.get_rel_pos(query_width, key_width, rel_pos_w) + + batch_size, _, dim = query.shape + reshaped_query = query.reshape(batch_size, query_height, query_width, dim) + rel_h = torch.einsum("bhwc,hkc->bhwk", reshaped_query, relative_position_height) + rel_w = torch.einsum("bhwc,wkc->bhwk", reshaped_query, relative_position_width) + + decomposed_rel_pos = rel_h[:, :, :, :, None] + rel_w[:, :, :, None, :] + + return decomposed_rel_pos + + def forward(self, hidden_states: torch.Tensor, output_attentions=None) -> tuple[torch.Tensor, torch.Tensor]: + batch_size, height, width, _ = hidden_states.shape + # qkv with shape (3, batch_size, nHead, height * width, channel) + qkv = ( + self.qkv(hidden_states) + .reshape(batch_size, height * width, 3, self.num_attention_heads, -1) + .permute(2, 0, 3, 1, 4) + ) + # q, k, v with shape (batch_size * nHead, height * width, channel) + query, key, value = qkv.reshape(3, batch_size * self.num_attention_heads, height * width, -1).unbind(0) + + attn_weights = (query * self.scale) @ key.transpose(-2, -1) + + if self.use_rel_pos: + decomposed_rel_pos = self.get_decomposed_rel_pos( + query, self.rel_pos_h, self.rel_pos_w, (height, width), (height, width) + ) + decomposed_rel_pos = decomposed_rel_pos.reshape_as(attn_weights) + attn_weights = attn_weights + decomposed_rel_pos + + attn_weights = torch.nn.functional.softmax(attn_weights, dtype=torch.float32, dim=-1).to(query.dtype) + + attn_probs = nn.functional.dropout(attn_weights, p=self.dropout, training=self.training) + + attn_output = (attn_probs @ value).reshape(batch_size, self.num_attention_heads, height, width, -1) + attn_output = attn_output.permute(0, 2, 3, 1, 4).reshape(batch_size, height, width, -1) + + attn_output = self.proj(attn_output) + return attn_output, attn_weights + + +class SamHQMLPBlock(nn.Module): + def __init__(self, config): + super().__init__() + self.lin1 = nn.Linear(config.hidden_size, config.mlp_dim) + self.lin2 = nn.Linear(config.mlp_dim, config.hidden_size) + self.act = ACT2FN[config.hidden_act] + + def forward(self, hidden_states: torch.Tensor) -> torch.Tensor: + hidden_states = self.lin1(hidden_states) + hidden_states = self.act(hidden_states) + hidden_states = self.lin2(hidden_states) + return hidden_states + + +class SamHQVisionSdpaAttention(SamHQVisionAttention): + """ + Multi-head Attention block with relative position embeddings. + Using SDPA instead of the default attention. + """ + + def __init__(self, config, window_size): + super().__init__(config, window_size) + + def forward(self, hidden_states: torch.Tensor, output_attentions=False) -> torch.Tensor: + if output_attentions: + logger.warning_once( + f"{self.__class__.__name__} does not support `output_attentions=True`. The returned attention weights will " + "be `None`. If you want to get attention weights, please set `attn_implementation='eager'` when loading the model." + ) + batch_size, height, width, _ = hidden_states.shape + # qkv with shape (3, B, nHead, H * W, C) + qkv = ( + self.qkv(hidden_states) + .reshape(batch_size, height * width, 3, self.num_attention_heads, -1) + .permute(2, 0, 3, 1, 4) + ) + # q, k, v with shape (B * nHead, H * W, C) + query, key, value = qkv.reshape(3, batch_size * self.num_attention_heads, height * width, -1).unbind(0) + + attn_bias = None + if self.use_rel_pos: + decomposed_rel_pos = self.get_decomposed_rel_pos( + query, self.rel_pos_h, self.rel_pos_w, (height, width), (height, width) + ) + decomposed_rel_pos = decomposed_rel_pos.reshape( + batch_size, self.num_attention_heads, height * width, height * width + ) + attn_bias = decomposed_rel_pos + + query = query.view(batch_size, self.num_attention_heads, height * width, -1) + key = key.view(batch_size, self.num_attention_heads, height * width, -1) + value = value.view(batch_size, self.num_attention_heads, height * width, -1) + + attn_output = torch.nn.functional.scaled_dot_product_attention(query, key, value, attn_mask=attn_bias) + + attn_output = ( + attn_output.view(batch_size, self.num_attention_heads, height, width, -1) + .permute(0, 2, 3, 1, 4) + .reshape(batch_size, height, width, -1) + ) + + attn_output = self.proj(attn_output) + return attn_output, None + + +SAM_HQ_VISION_ATTENTION_CLASSES = { + "eager": SamHQVisionAttention, + "sdpa": SamHQVisionSdpaAttention, +} + + +class SamHQVisionLayer(GradientCheckpointingLayer): + def __init__(self, config, window_size): + super().__init__() + self.layer_norm1 = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps) + self.attn = SAM_HQ_VISION_ATTENTION_CLASSES[config._attn_implementation](config, window_size) + self.layer_norm2 = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps) + self.mlp = SamHQMLPBlock(config) + self.window_size = window_size + + def window_partition(self, hidden_states: torch.Tensor, window_size: int) -> tuple[torch.Tensor, tuple[int, int]]: + """ + Args: + Partition into non-overlapping windows with padding if needed. + hidden_states (tensor): input tokens with [batch_size, height, width, channel]. window_size (int): window + size. + + Returns: + windows: windows after partition with [batch_size * num_windows, window_size, window_size, channel]. + (pad_height, pad_width): padded height and width before partition + """ + batch_size, height, width, channel = hidden_states.shape + + pad_h = (window_size - height % window_size) % window_size + pad_w = (window_size - width % window_size) % window_size + hidden_states = F.pad(hidden_states, (0, 0, 0, pad_w, 0, pad_h)) + pad_height, pad_width = height + pad_h, width + pad_w + + hidden_states = hidden_states.reshape( + batch_size, pad_height // window_size, window_size, pad_width // window_size, window_size, channel + ) + windows = hidden_states.permute(0, 1, 3, 2, 4, 5).contiguous().reshape(-1, window_size, window_size, channel) + return windows, (pad_height, pad_width) + + def window_unpartition( + self, windows: torch.Tensor, window_size: int, padding_shape: tuple[int, int], original_shape: tuple[int, int] + ) -> torch.Tensor: + """ + Args: + Window unpartition into original sequences and removing padding. + hidden_states (tensor): + input tokens with [batch_size * num_windows, window_size, window_size, channel]. + window_size (int): + window size. + padding_shape (Tuple): + padded height and width (pad_height, pad_width). + original_shape (Tuple): original height and width (height, width) before padding. + + Returns: + hidden_states: unpartitioned sequences with [batch_size, height, width, channel]. + """ + pad_height, pad_width = padding_shape + height, width = original_shape + batch_size = windows.shape[0] // (pad_height * pad_width // window_size // window_size) + hidden_states = windows.reshape( + batch_size, pad_height // window_size, pad_width // window_size, window_size, window_size, -1 + ) + hidden_states = ( + hidden_states.permute(0, 1, 3, 2, 4, 5).contiguous().reshape(batch_size, pad_height, pad_width, -1) + ) + + hidden_states = hidden_states[:, :height, :width, :].contiguous() + return hidden_states + + def forward(self, hidden_states: torch.Tensor) -> tuple[torch.FloatTensor]: + residual = hidden_states + hidden_states = self.layer_norm1(hidden_states) + # Window partition + if self.window_size > 0: + height, width = hidden_states.shape[1], hidden_states.shape[2] + hidden_states, padding_shape = self.window_partition(hidden_states, self.window_size) + + hidden_states, attn_weights = self.attn( + hidden_states=hidden_states, + ) + # Reverse window partition + if self.window_size > 0: + hidden_states = self.window_unpartition(hidden_states, self.window_size, padding_shape, (height, width)) + + hidden_states = residual + hidden_states + layernorm_output = self.layer_norm2(hidden_states) + hidden_states = hidden_states + self.mlp(layernorm_output) + return hidden_states + + +class SamHQPositionalEmbedding(nn.Module): + def __init__(self, config): + super().__init__() + self.scale = config.scale + self.positional_embedding = nn.Parameter(self.scale * torch.randn((2, config.num_pos_feats))) + + def forward(self, input_coords, input_shape=None): + """Positionally encode points that are normalized to [0,1].""" + coordinates = input_coords.clone() + + if input_shape is not None: + coordinates[:, :, :, 0] = coordinates[:, :, :, 0] / input_shape[1] + coordinates[:, :, :, 1] = coordinates[:, :, :, 1] / input_shape[0] + + # assuming coords are in [0, 1]^2 square and have d_1 x ... x d_n x 2 shape + coordinates = 2 * coordinates - 1 + coordinates = coordinates.to(self.positional_embedding.dtype) + coordinates = coordinates @ self.positional_embedding + coordinates = 2 * np.pi * coordinates + # outputs d_1 x ... x d_n x channel shape + return torch.cat([torch.sin(coordinates), torch.cos(coordinates)], dim=-1) + + +@auto_docstring +class SamHQPreTrainedModel(PreTrainedModel): + config: SamHQConfig + base_model_prefix = "sam_hq" + main_input_name = "pixel_values" + input_modalities = ("image",) + _no_split_modules = ["SamHQVisionAttention"] + supports_gradient_checkpointing = True + _supports_sdpa = True + + @torch.no_grad() + def _init_weights(self, module: nn.Module): + super()._init_weights(module) + if isinstance(module, SamHQVisionAttention): + if module.use_rel_pos: + init.zeros_(module.rel_pos_h) + init.zeros_(module.rel_pos_w) + elif isinstance(module, SamHQVisionEncoder): + if self.config.use_abs_pos: + init.zeros_(module.pos_embed) + elif isinstance(module, SamHQPositionalEmbedding): + init.normal_(module.positional_embedding, std=module.scale) + + +class SamHQPatchEmbeddings(nn.Module): + """ + This class turns `pixel_values` of shape `(batch_size, num_channels, height, width)` into the initial + `hidden_states` (patch embeddings) of shape `(batch_size, seq_length, hidden_size)` to be consumed by a + Transformer. + """ + + def __init__(self, config): + super().__init__() + image_size, patch_size = config.image_size, config.patch_size + num_channels, hidden_size = config.num_channels, config.hidden_size + image_size = image_size if isinstance(image_size, collections.abc.Iterable) else (image_size, image_size) + patch_size = patch_size if isinstance(patch_size, collections.abc.Iterable) else (patch_size, patch_size) + num_patches = (image_size[1] // patch_size[1]) * (image_size[0] // patch_size[0]) + self.image_size = image_size + self.patch_size = patch_size + self.num_channels = num_channels + self.num_patches = num_patches + + self.projection = nn.Conv2d(num_channels, hidden_size, kernel_size=patch_size, stride=patch_size) + + def forward(self, pixel_values): + batch_size, num_channels, height, width = pixel_values.shape + if num_channels != self.num_channels: + raise ValueError( + "Make sure that the channel dimension of the pixel values match with the one set in the configuration." + ) + if height != self.image_size[0] or width != self.image_size[1]: + raise ValueError( + f"Input image size ({height}*{width}) doesn't match model ({self.image_size[0]}*{self.image_size[1]})." + ) + embeddings = self.projection(pixel_values).permute(0, 2, 3, 1) + return embeddings + + +class SamHQVisionNeck(nn.Module): + def __init__(self, config: SamHQVisionConfig): + super().__init__() + self.config = config + + self.conv1 = nn.Conv2d(config.hidden_size, config.output_channels, kernel_size=1, bias=False) + self.layer_norm1 = SamHQLayerNorm(config.output_channels, data_format="channels_first") + self.conv2 = nn.Conv2d(config.output_channels, config.output_channels, kernel_size=3, padding=1, bias=False) + self.layer_norm2 = SamHQLayerNorm(config.output_channels, data_format="channels_first") + + def forward(self, hidden_states): + hidden_states = hidden_states.permute(0, 3, 1, 2) + hidden_states = self.conv1(hidden_states) + hidden_states = self.layer_norm1(hidden_states) + + hidden_states = self.conv2(hidden_states) + hidden_states = self.layer_norm2(hidden_states) + return hidden_states + + +class SamHQVisionEncoder(SamHQPreTrainedModel): + _can_record_outputs = { + "hidden_states": SamHQVisionLayer, + "attentions": SamHQVisionAttention, + } + + def __init__(self, config: SamHQVisionConfig): + super().__init__(config) + self.config = config + self.image_size = config.image_size + self.patch_embed = SamHQPatchEmbeddings(config) + + self.pos_embed = None + if config.use_abs_pos: + # Initialize absolute positional embedding with pretrain image size. + self.pos_embed = nn.Parameter( + torch.zeros( + 1, + config.image_size // config.patch_size, + config.image_size // config.patch_size, + config.hidden_size, + ) + ) + + self.layers = nn.ModuleList() + for i in range(config.num_hidden_layers): + layer = SamHQVisionLayer( + config, + window_size=config.window_size if i not in config.global_attn_indexes else 0, + ) + self.layers.append(layer) + + self.neck = SamHQVisionNeck(config) + + self.gradient_checkpointing = False + self.post_init() + + def get_input_embeddings(self): + return self.patch_embed + + @merge_with_config_defaults + @capture_outputs(tie_last_hidden_states=False) + def forward( + self, pixel_values: torch.FloatTensor | None = None, **kwargs: Unpack[TransformersKwargs] + ) -> tuple | SamHQVisionEncoderOutput: + if pixel_values is None: + raise ValueError("You have to specify pixel_values") + + hidden_states = self.patch_embed(pixel_values) + if self.pos_embed is not None: + hidden_states = hidden_states + self.pos_embed + + intermediate_embeddings = [] + + for layer_module in self.layers: + hidden_states = layer_module(hidden_states) + + # Collect embeddings from non-windowed blocks + if hasattr(layer_module, "window_size") and layer_module.window_size == 0: + intermediate_embeddings.append(hidden_states) + + hidden_states = self.neck(hidden_states) + + return SamHQVisionEncoderOutput( + last_hidden_state=hidden_states, + intermediate_embeddings=intermediate_embeddings, + ) + + +class SamHQLayerNorm(nn.LayerNorm): + r"""LayerNorm that supports two data formats: channels_last (default) or channels_first. + The ordering of the dimensions in the inputs. channels_last corresponds to inputs with shape (batch_size, height, + width, channels) while channels_first corresponds to inputs with shape (batch_size, channels, height, width). + """ + + def __init__(self, normalized_shape, *, eps=1e-6, data_format="channels_last", **kwargs): + super().__init__(normalized_shape, eps=eps, **kwargs) + if data_format not in ["channels_last", "channels_first"]: + raise NotImplementedError(f"Unsupported data format: {data_format}") + self.data_format = data_format + + def forward(self, features: torch.Tensor) -> torch.Tensor: + """ + Args: + features: Tensor of shape (batch_size, channels, height, width) OR (batch_size, height, width, channels) + """ + if self.data_format == "channels_first": + features = features.permute(0, 2, 3, 1) + features = super().forward(features) + features = features.permute(0, 3, 1, 2) + else: + features = super().forward(features) + return features + + +def eager_attention_forward( + module: nn.Module, + query: torch.Tensor, + key: torch.Tensor, + value: torch.Tensor, + attention_mask: torch.Tensor | None, + scaling: float, + dropout: float = 0.0, + **kwargs, +): + attn_weights = torch.matmul(query, key.transpose(2, 3)) * scaling + if attention_mask is not None: + attn_weights = attn_weights + attention_mask + + attn_weights = nn.functional.softmax(attn_weights, dim=-1, dtype=torch.float32).to(query.dtype) + attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training) + attn_output = torch.matmul(attn_weights, value) + attn_output = attn_output.transpose(1, 2).contiguous() + + return attn_output, attn_weights + + +class SamHQAttention(nn.Module): + """ + SAM_HQ's attention layer that allows for downscaling the size of the embedding after projection to queries, keys, and + values. + """ + + def __init__(self, config, downsample_rate=None): + super().__init__() + self.config = config + self.hidden_size = config.hidden_size + + downsample_rate = config.attention_downsample_rate if downsample_rate is None else downsample_rate + + self.internal_dim = config.hidden_size // downsample_rate + self.num_attention_heads = config.num_attention_heads + if self.internal_dim % config.num_attention_heads != 0: + raise ValueError("num_attention_heads must divide hidden_size.") + self.scaling = (self.internal_dim // config.num_attention_heads) ** -0.5 + + self.q_proj = nn.Linear(self.hidden_size, self.internal_dim) + self.k_proj = nn.Linear(self.hidden_size, self.internal_dim) + self.v_proj = nn.Linear(self.hidden_size, self.internal_dim) + self.out_proj = nn.Linear(self.internal_dim, self.hidden_size) + + self.is_causal = False + + def _separate_heads(self, hidden_states: Tensor, num_attention_heads: int) -> Tensor: + batch, point_batch_size, n_tokens, channel = hidden_states.shape + c_per_head = channel // num_attention_heads + hidden_states = hidden_states.reshape(batch * point_batch_size, n_tokens, num_attention_heads, c_per_head) + return hidden_states.transpose(1, 2) + + def _recombine_heads(self, hidden_states: Tensor, point_batch_size: int) -> Tensor: + batch, n_tokens, n_heads, c_per_head = hidden_states.shape + return hidden_states.reshape(batch // point_batch_size, point_batch_size, n_tokens, n_heads * c_per_head) + + def forward( + self, + query: Tensor, + key: Tensor, + value: Tensor, + attention_similarity: Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> Tensor: + # Input projections + query = self.q_proj(query) + key = self.k_proj(key) + value = self.v_proj(value) + + point_batch_size = query.shape[1] + # Separate into heads + query = self._separate_heads(query, self.num_attention_heads) + key = self._separate_heads(key, self.num_attention_heads) + value = self._separate_heads(value, self.num_attention_heads) + + # SamHQAttention + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, eager_attention_forward + ) + + attn_output, attn_weights = attention_interface( + self, + query, + key, + value, + attention_mask=attention_similarity, + dropout=0.0, + scaling=self.scaling, + is_causal=self.is_causal, + **kwargs, + ) + + attn_output = self._recombine_heads(attn_output, point_batch_size) + attn_output = self.out_proj(attn_output) + + return attn_output, attn_weights + + +class SamHQTwoWayAttentionBlock(nn.Module): + def __init__(self, config, attention_downsample_rate: int = 2, skip_first_layer_pe: bool = False): + """ + A transformer block with four layers: + (1) self-attention of sparse inputs (2) cross attention of sparse inputs -> dense inputs (3) mlp block on + sparse inputs (4) cross attention of dense inputs -> sparse inputs + + Arguments: + config (`SamHQMaskDecoderConfig`): + The configuration file used to instantiate the block + attention_downsample_rate (*optionalk*, int, defaults to 2): + The downsample ratio of the block used to reduce the inner dim of the attention. + skip_first_layer_pe (*optional*, bool, defaults to `False`): + Whether or not to skip the addition of the query_point_embedding on the first layer. + """ + super().__init__() + + self.hidden_size = config.hidden_size + self.layer_norm_eps = config.layer_norm_eps + + self.self_attn = SamHQAttention(config, downsample_rate=1) + self.layer_norm1 = nn.LayerNorm(self.hidden_size, eps=self.layer_norm_eps) + + self.cross_attn_token_to_image = SamHQAttention(config, downsample_rate=attention_downsample_rate) + self.layer_norm2 = nn.LayerNorm(self.hidden_size, eps=self.layer_norm_eps) + + self.mlp = SamHQMLPBlock(config) + self.layer_norm3 = nn.LayerNorm(self.hidden_size, eps=self.layer_norm_eps) + + self.layer_norm4 = nn.LayerNorm(self.hidden_size, eps=self.layer_norm_eps) + self.cross_attn_image_to_token = SamHQAttention(config, downsample_rate=attention_downsample_rate) + self.skip_first_layer_pe = skip_first_layer_pe + + def forward( + self, + queries: Tensor, + keys: Tensor, + query_point_embedding: Tensor, + key_point_embedding: Tensor, + attention_similarity: Tensor, + **kwargs: Unpack[TransformersKwargs], + ): + # Self attention block + if self.skip_first_layer_pe: + queries, _ = self.self_attn(query=queries, key=queries, value=queries) + else: + query = queries + query_point_embedding + attn_out, _ = self.self_attn(query=query, key=query, value=queries) + queries = queries + attn_out + queries = self.layer_norm1(queries) + + # Cross attention block, tokens attending to image embedding + query = queries + query_point_embedding + key = keys + key_point_embedding + + attn_out, _ = self.cross_attn_token_to_image( + query=query, key=key, value=keys, attention_similarity=attention_similarity + ) + queries = queries + attn_out + + queries = self.layer_norm2(queries) + + # MLP block + mlp_out = self.mlp(queries) + queries = queries + mlp_out + queries = self.layer_norm3(queries) + + # Cross attention block, image embedding attending to tokens + query = queries + query_point_embedding + key = keys + key_point_embedding + + attn_out, _ = self.cross_attn_image_to_token(query=key, key=query, value=queries) + keys = keys + attn_out + + keys = self.layer_norm4(keys) + return queries, keys, attn_out + + +class SamHQTwoWayTransformer(nn.Module): + def __init__(self, config: SamHQMaskDecoderConfig): + super().__init__() + self.config = config + + self.num_hidden_layers = config.num_hidden_layers + self.layers = nn.ModuleList() + + for i in range(self.num_hidden_layers): + self.layers.append(SamHQTwoWayAttentionBlock(config, skip_first_layer_pe=(i == 0))) + + self.final_attn_token_to_image = SamHQAttention(config) + self.layer_norm_final_attn = nn.LayerNorm(config.hidden_size) + + def forward( + self, + point_embeddings: Tensor, + image_embeddings: Tensor, + image_positional_embeddings: Tensor, + attention_similarity: Tensor, + target_embedding=None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple | BaseModelOutput: + if image_embeddings is None: + raise ValueError("You have to specify an image_embedding") + + image_embeddings = image_embeddings.flatten(2).permute(0, 2, 1).unsqueeze(1) + image_positional_embeddings = image_positional_embeddings.flatten(2).permute(0, 2, 1).unsqueeze(1) + + # Prepare queries + queries = point_embeddings + keys = image_embeddings + + # Apply transformer blocks and final layernorm + for layer in self.layers: + if target_embedding is not None: + queries += target_embedding + + queries, keys, _ = layer( + queries=queries, + keys=keys, + query_point_embedding=point_embeddings, + key_point_embedding=image_positional_embeddings, + attention_similarity=attention_similarity, + **kwargs, + ) + # Apply the final attention layer from the points to the image + query = queries + point_embeddings + key = keys + image_positional_embeddings + + attn_out, _ = self.final_attn_token_to_image(query=query, key=key, value=keys) + + queries = queries + attn_out + queries = self.layer_norm_final_attn(queries) + return queries, keys + + +class SamHQFeedForward(nn.Module): + def __init__( + self, input_dim: int, hidden_dim: int, output_dim: int, num_layers: int, sigmoid_output: bool = False + ): + super().__init__() + self.num_layers = num_layers + self.activation = nn.ReLU() + self.proj_in = nn.Linear(input_dim, hidden_dim) + self.proj_out = nn.Linear(hidden_dim, output_dim) + self.layers = nn.ModuleList([nn.Linear(hidden_dim, hidden_dim) for _ in range(num_layers - 2)]) + self.sigmoid_output = sigmoid_output + + def forward(self, hidden_states): + hidden_states = self.proj_in(hidden_states) + hidden_states = self.activation(hidden_states) + for layer in self.layers: + hidden_states = self.activation(layer(hidden_states)) + + hidden_states = self.proj_out(hidden_states) + if self.sigmoid_output: + hidden_states = F.sigmoid(hidden_states) + return hidden_states + + +class SamHQMaskDecoder(nn.Module): + def __init__(self, config: SamHQMaskDecoderConfig): + super().__init__() + self.hidden_size = config.hidden_size + + self.num_multimask_outputs = config.num_multimask_outputs + self.num_mask_tokens = config.num_multimask_outputs + 1 + + self.iou_token = nn.Embedding(1, self.hidden_size) + self.mask_tokens = nn.Embedding(self.num_mask_tokens, self.hidden_size) + + self.transformer = SamHQTwoWayTransformer(config) + + self.upscale_conv1 = nn.ConvTranspose2d(self.hidden_size, self.hidden_size // 4, kernel_size=2, stride=2) + self.upscale_conv2 = nn.ConvTranspose2d(self.hidden_size // 4, self.hidden_size // 8, kernel_size=2, stride=2) + self.upscale_layer_norm = SamHQLayerNorm(self.hidden_size // 4, data_format="channels_first") + self.activation = nn.GELU() + + mlps_list = [] + for _ in range(self.num_mask_tokens): + mlps_list += [SamHQFeedForward(self.hidden_size, self.hidden_size, self.hidden_size // 8, 3)] + self.output_hypernetworks_mlps = nn.ModuleList(mlps_list) + + self.iou_prediction_head = SamHQFeedForward( + self.hidden_size, config.iou_head_hidden_dim, self.num_mask_tokens, config.iou_head_depth + ) + + self.hq_token = nn.Embedding(1, self.hidden_size) + self.hq_mask_mlp = SamHQFeedForward(self.hidden_size, self.hidden_size, self.hidden_size // 8, 3) + self.num_mask_tokens = self.num_mask_tokens + 1 + + # Compress ViT features + self.compress_vit_conv1 = nn.ConvTranspose2d(config.vit_dim, self.hidden_size, kernel_size=2, stride=2) + self.compress_vit_norm = SamHQLayerNorm(self.hidden_size, data_format="channels_first") + self.compress_vit_conv2 = nn.ConvTranspose2d(self.hidden_size, self.hidden_size // 8, kernel_size=2, stride=2) + + # Embedding encoder + self.encoder_conv1 = nn.ConvTranspose2d(self.hidden_size, self.hidden_size // 4, kernel_size=2, stride=2) + self.encoder_norm = SamHQLayerNorm(self.hidden_size // 4, data_format="channels_first") + self.encoder_conv2 = nn.ConvTranspose2d(self.hidden_size // 4, self.hidden_size // 8, kernel_size=2, stride=2) + + # Embedding mask feature + self.mask_conv1 = nn.Conv2d(self.hidden_size // 8, self.hidden_size // 4, kernel_size=3, stride=1, padding=1) + self.mask_norm = SamHQLayerNorm(self.hidden_size // 4, data_format="channels_first") + self.mask_conv2 = nn.Conv2d(self.hidden_size // 4, self.hidden_size // 8, kernel_size=3, stride=1, padding=1) + + def forward( + self, + image_embeddings: torch.Tensor, + image_positional_embeddings: torch.Tensor, + sparse_prompt_embeddings: torch.Tensor, + dense_prompt_embeddings: torch.Tensor, + multimask_output: bool, + hq_token_only: bool, + intermediate_embeddings: list[torch.Tensor] | None = None, + attention_similarity: torch.Tensor | None = None, + target_embedding: torch.Tensor | None = None, + ) -> SamHQMMaskDecoderOutputs: + """ + Predict high-quality masks given image and prompt embeddings. + + Args: + image_embeddings (`torch.Tensor`): + The embeddings from the image encoder. + image_positional_embedding (`torch.Tensor`): + Positional encoding with the shape of image_embeddings. + sparse_prompt_embeddings (`torch.Tensor`): + The embeddings of the points and boxes. + dense_prompt_embeddings (`torch.Tensor`): + The embeddings of the mask inputs. + multimask_output (bool): + Whether to return multiple masks or a single mask. + hq_token_only (bool): + Whether to use only the high-quality token output or combine with SAM output. + intermediate_embeddings (`torch.Tensor`): + Intermediate embeddings from the vision encoder for feature fusion. + attention_similarity (`torch.Tensor`, *optional*): + Optional tensor for attention similarity computation. + target_embedding (`torch.Tensor`, *optional*): + Optional target embedding for transformer processing. + + Returns: + `Tuple[torch.Tensor, torch.Tensor, Optional[torch.Tensor]]`: A tuple of tensors containing: + - A tensor of shape `(batch_size, num_prompts, num_masks, height, width)` containing the output masks. + - A tensor of shape `(batch_size, num_prompts, num_masks)` containing the iou predictions for each mask. + - (Optional) A tuple containing attention tensors if output_attentions is True. + """ + batch_size, num_channels, height, width = image_embeddings.shape + point_batch_size = sparse_prompt_embeddings.shape[1] if sparse_prompt_embeddings is not None else 1 + + has_intermediate = intermediate_embeddings is not None and len(intermediate_embeddings) > 0 + + if has_intermediate: + vit_features = intermediate_embeddings[0].permute(0, 3, 1, 2).contiguous() + + embed_encode = self.encoder_conv1(image_embeddings) + embed_encode = self.activation(self.encoder_norm(embed_encode)) + embed_encode = self.encoder_conv2(embed_encode) + + if has_intermediate: + compressed_vit_features = self.compress_vit_conv1(vit_features) + compressed_vit_features = self.activation(self.compress_vit_norm(compressed_vit_features)) + compressed_vit_features = self.compress_vit_conv2(compressed_vit_features) + + hq_features = embed_encode + compressed_vit_features + else: + hq_features = embed_encode + + output_tokens = torch.cat([self.iou_token.weight, self.mask_tokens.weight, self.hq_token.weight], dim=0) + output_tokens = output_tokens.repeat(batch_size, point_batch_size, 1, 1) + + if sparse_prompt_embeddings is not None: + tokens = torch.cat([output_tokens, sparse_prompt_embeddings], dim=2) + else: + tokens = output_tokens + point_embeddings = tokens.to(self.iou_token.weight.dtype) + image_embeddings = image_embeddings + dense_prompt_embeddings + image_embeddings = image_embeddings.repeat_interleave(point_batch_size, 0) + image_positional_embeddings = image_positional_embeddings.repeat_interleave(point_batch_size, 0) + + point_embedding, iou_token_out = self.transformer( + point_embeddings=point_embeddings, + image_embeddings=image_embeddings, + image_positional_embeddings=image_positional_embeddings, + attention_similarity=attention_similarity, + target_embedding=target_embedding, + ) + iou_token_out = point_embedding[:, :, 0, :] + mask_tokens_out = point_embedding[:, :, 1 : (1 + self.num_mask_tokens), :] + + image_embeddings = image_embeddings.transpose(2, 3).reshape( + batch_size * point_batch_size, num_channels, height, width + ) + + upscaled_embedding = self.upscale_conv1(image_embeddings) + upscaled_embedding = self.activation(self.upscale_layer_norm(upscaled_embedding)) + upscaled_embedding = self.activation(self.upscale_conv2(upscaled_embedding)) + + upscaled_embedding_hq = self.mask_conv1(upscaled_embedding) + upscaled_embedding_hq = self.activation(self.mask_norm(upscaled_embedding_hq)) + upscaled_embedding_hq = self.mask_conv2(upscaled_embedding_hq) + + if hq_features.shape[0] == 1: + hq_features = hq_features.repeat(batch_size * point_batch_size, 1, 1, 1) + elif hq_features.shape[0] == batch_size and batch_size * point_batch_size != batch_size: + hq_features = hq_features.repeat_interleave(point_batch_size, 0) + upscaled_embedding_hq = upscaled_embedding_hq + hq_features + + hyper_in_list = [] + for mask_token_index in range(self.num_mask_tokens): + if mask_token_index < self.num_mask_tokens - 1: + current_mlp = self.output_hypernetworks_mlps[mask_token_index] + else: + current_mlp = self.hq_mask_mlp + hyper_in_list += [current_mlp(mask_tokens_out[:, :, mask_token_index, :])] + + hyper_in = torch.stack(hyper_in_list, dim=2) + _, num_channels, height, width = upscaled_embedding.shape + upscaled_embedding = upscaled_embedding.reshape(batch_size, point_batch_size, num_channels, height * width) + upscaled_embedding_hq = upscaled_embedding_hq.reshape( + batch_size, point_batch_size, num_channels, height * width + ) + + masks_sam = (hyper_in[:, :, : self.num_mask_tokens - 1] @ upscaled_embedding).reshape( + batch_size, point_batch_size, -1, height, width + ) + masks_hq = (hyper_in[:, :, self.num_mask_tokens - 1 :] @ upscaled_embedding_hq).reshape( + batch_size, point_batch_size, -1, height, width + ) + masks = torch.cat([masks_sam, masks_hq], dim=2) + + iou_pred = self.iou_prediction_head(iou_token_out) + + if multimask_output: + mask_slice = slice(1, self.num_mask_tokens - 1) + iou_pred = iou_pred[:, :, mask_slice] + # Sort the IoU scores in descending order and get indices + iou_pred_sorted, sort_indices = torch.sort(iou_pred, dim=2, descending=True) + # Reorder the masks according to sorted scores + masks_sam = masks[:, :, mask_slice, :, :] + masks_sam = torch.gather( + masks_sam, + 2, + sort_indices[..., None, None].expand(-1, -1, -1, masks_sam.shape[3], masks_sam.shape[4]), + ) + # Update iou_pred with sorted scores + iou_pred = iou_pred_sorted + else: + mask_slice = slice(0, 1) + iou_pred = iou_pred[:, :, mask_slice] + masks_sam = masks[:, :, mask_slice, :, :] + + masks_hq = masks[:, :, slice(self.num_mask_tokens - 1, self.num_mask_tokens), :, :] + if hq_token_only: + masks = masks_hq + else: + masks = masks_sam + masks_hq + + return masks, iou_pred + + +@auto_docstring( + custom_intro=""" + The vision model from SamHQ without any head or projection on top. + """ +) +class SamHQVisionModel(SamHQPreTrainedModel): + config: SamHQVisionConfig + main_input_name = "pixel_values" + + def __init__(self, config: SamHQVisionConfig): + super().__init__(config) + self.vision_encoder = SamHQVisionEncoder(config) + self.post_init() + + def get_input_embeddings(self) -> nn.Module: + return self.vision_encoder.patch_embed + + @auto_docstring + def forward( + self, + pixel_values: torch.FloatTensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple | SamHQVisionEncoderOutput: + return self.vision_encoder(pixel_values, **kwargs) + + +class SamHQMaskEmbedding(nn.Module): + def __init__(self, config: SamHQPromptEncoderConfig): + super().__init__() + self.mask_input_channels = config.mask_input_channels // 4 + self.activation = ACT2FN[config.hidden_act] + self.conv1 = nn.Conv2d(1, self.mask_input_channels, kernel_size=2, stride=2) + self.conv2 = nn.Conv2d(self.mask_input_channels, config.mask_input_channels, kernel_size=2, stride=2) + self.conv3 = nn.Conv2d(config.mask_input_channels, config.hidden_size, kernel_size=1) + self.layer_norm1 = SamHQLayerNorm( + self.mask_input_channels, eps=config.layer_norm_eps, data_format="channels_first" + ) + self.layer_norm2 = SamHQLayerNorm( + self.mask_input_channels * 4, eps=config.layer_norm_eps, data_format="channels_first" + ) + + def forward(self, masks): + hidden_states = self.conv1(masks) + hidden_states = self.layer_norm1(hidden_states) + hidden_states = self.activation(hidden_states) + + hidden_states = self.conv2(hidden_states) + hidden_states = self.layer_norm2(hidden_states) + hidden_states = self.activation(hidden_states) + dense_embeddings = self.conv3(hidden_states) + return dense_embeddings + + +class SamHQPromptEncoder(nn.Module): + def __init__(self, config: SamHQConfig): + super().__init__() + self.shared_embedding = SamHQPositionalEmbedding(config.vision_config) + config = config.prompt_encoder_config + self.mask_embed = SamHQMaskEmbedding(config) + self.no_mask_embed = nn.Embedding(1, config.hidden_size) + + self.image_embedding_size = (config.image_embedding_size, config.image_embedding_size) + self.input_image_size = config.image_size + + self.point_embed = nn.ModuleList( + [nn.Embedding(1, config.hidden_size) for i in range(config.num_point_embeddings)] + ) + self.hidden_size = config.hidden_size + self.not_a_point_embed = nn.Embedding(1, config.hidden_size) + + def _embed_points(self, points: torch.Tensor, labels: torch.Tensor, pad: bool) -> torch.Tensor: + """Embeds point prompts.""" + points = points + 0.5 # Shift to center of pixel + if pad: + target_point_shape = (points.shape[0], points.shape[1], 1, points.shape[-1]) + target_labels_shape = (points.shape[0], points.shape[1], 1) + padding_point = torch.zeros(target_point_shape, device=points.device) + padding_label = -torch.ones(target_labels_shape, device=labels.device) + points = torch.cat([points, padding_point], dim=2) + labels = torch.cat([labels, padding_label], dim=2) + input_shape = (self.input_image_size, self.input_image_size) + point_embedding = self.shared_embedding(points, input_shape) + + # torch.where and expanding the labels tensor is required by the ONNX export + point_embedding = torch.where(labels[..., None] == -1, self.not_a_point_embed.weight, point_embedding) + + # This is required for the ONNX export. The dtype, device need to be explicitly + # specified as otherwise torch.onnx.export interprets as double + point_embedding = torch.where(labels[..., None] != -10, point_embedding, torch.zeros_like(point_embedding)) + + point_embedding = torch.where( + (labels == 0)[:, :, :, None], + point_embedding + self.point_embed[0].weight[None, None, :, :], + point_embedding, + ) + + point_embedding = torch.where( + (labels == 1)[:, :, :, None], + point_embedding + self.point_embed[1].weight[None, None, :, :], + point_embedding, + ) + + return point_embedding + + def _embed_boxes(self, boxes: torch.Tensor) -> torch.Tensor: + """Embeds box prompts.""" + boxes = boxes + 0.5 # Shift to center of pixel + batch_size, nb_boxes = boxes.shape[:2] + coords = boxes.reshape(batch_size, nb_boxes, 2, 2) + input_shape = (self.input_image_size, self.input_image_size) + corner_embedding = self.shared_embedding(coords, input_shape) + corner_embedding[:, :, 0, :] += self.point_embed[2].weight + corner_embedding[:, :, 1, :] += self.point_embed[3].weight + return corner_embedding + + def forward( + self, + input_points: tuple[torch.Tensor, torch.Tensor] | None, + input_labels: torch.Tensor | None, + input_boxes: torch.Tensor | None, + input_masks: torch.Tensor | None, + ) -> tuple[torch.Tensor, torch.Tensor]: + """ + Embeds different types of prompts, returning both sparse and dense embeddings. + + Args: + points (`torch.Tensor`, *optional*): + point coordinates and labels to embed. + boxes (`torch.Tensor`, *optional*): + boxes to embed + masks (`torch.Tensor`, *optional*): + masks to embed + """ + sparse_embeddings = None + batch_size = 1 + if input_points is not None: + batch_size = input_points.shape[0] + if input_labels is None: + raise ValueError("If points are provided, labels must also be provided.") + point_embeddings = self._embed_points(input_points, input_labels, pad=(input_boxes is None)) + sparse_embeddings = point_embeddings + if input_boxes is not None: + batch_size = input_boxes.shape[0] + box_embeddings = self._embed_boxes(input_boxes) + if sparse_embeddings is None: + sparse_embeddings = box_embeddings + else: + sparse_embeddings = torch.cat([sparse_embeddings, box_embeddings], dim=2) + if input_masks is not None: + dense_embeddings = self.mask_embed(input_masks) + else: + dense_embeddings = self.no_mask_embed.weight.reshape(1, -1, 1, 1).expand( + batch_size, -1, self.image_embedding_size[0], self.image_embedding_size[1] + ) + + return sparse_embeddings, dense_embeddings + + +@auto_docstring( + custom_intro=""" + Segment Anything Model HQ (SAM-HQ) for generating masks, given an input image and optional 2D location and bounding boxes. + """ +) +class SamHQModel(SamHQPreTrainedModel): + input_modalities = ("image", "text") + _can_record_outputs = {"mask_decoder_attentions": OutputRecorder(SamHQTwoWayAttentionBlock, index=2)} + _tied_weights_keys = { + "prompt_encoder.shared_embedding.positional_embedding": "shared_image_embedding.positional_embedding" + } + + def __init__(self, config): + super().__init__(config) + self.shared_image_embedding = SamHQPositionalEmbedding(config.vision_config) + self.vision_encoder = SamHQVisionEncoder(config.vision_config) + self.prompt_encoder = SamHQPromptEncoder(config) + # The module using it is not a PreTrainedModel subclass so we need this + config.mask_decoder_config._attn_implementation = config._attn_implementation + + self.mask_decoder = SamHQMaskDecoder(config.mask_decoder_config) + self.post_init() + + def get_input_embeddings(self): + return self.vision_encoder.get_input_embeddings() + + def get_image_wide_positional_embeddings(self): + size = self.config.prompt_encoder_config.image_embedding_size + target_device = self.shared_image_embedding.positional_embedding.device + target_dtype = self.shared_image_embedding.positional_embedding.dtype + grid = torch.ones((size, size), device=target_device, dtype=target_dtype) + y_embed = grid.cumsum(dim=0) - 0.5 + x_embed = grid.cumsum(dim=1) - 0.5 + y_embed = y_embed / size + x_embed = x_embed / size + + positional_embedding = self.shared_image_embedding(torch.stack([x_embed, y_embed], dim=-1)) + return positional_embedding.permute(2, 0, 1).unsqueeze(0) # channel x height x width + + @torch.no_grad() + def get_image_embeddings( + self, + pixel_values, + ): + r""" + Returns the image embeddings by passing the pixel values through the vision encoder. + + Args: + pixel_values (`torch.FloatTensor` of shape `(batch_size, num_channels, height, width)`): + Input pixel values + """ + vision_output = self.vision_encoder(pixel_values=pixel_values) + image_embeddings = vision_output[0] + intermediate_embeddings = vision_output[1] + return image_embeddings, intermediate_embeddings + + @torch.no_grad() + def get_prompt_embeddings( + self, + input_points: torch.FloatTensor | None = None, + input_labels: torch.LongTensor | None = None, + input_boxes: torch.FloatTensor | None = None, + input_masks: torch.LongTensor | None = None, + ): + r""" + Returns the prompt embeddings by passing the input points, labels, boxes and masks through the prompt encoder. + + Args: + input_points (`torch.FloatTensor` of shape `(batch_size, point_batch_size, num_points_per_image, 2)`): + Optional input points for the prompt encoder. The padding of the point is automatically done by the + processor. `point_batch_size` refers to the number of masks that we want the model to predict per + point. The model will output `point_batch_size` times 3 masks in total. + input_labels (`torch.LongTensor` of shape `(batch_size, point_batch_size, num_points_per_image)`): + Optional input labels for the prompt encoder. The padding of the labels is automatically done by the + processor, or can be fed by the user. + input_boxes (`torch.FloatTensor` of shape `(batch_size, num_boxes_per_image, 4)`): + Optional input boxes for the prompt encoder. The padding of the boxes is automatically done by the + processor. users can also pass manually the input boxes. + input_masks (`torch.LongTensor` of shape `(batch_size, image_size, image_size)`): + Optional input masks for the prompt encoder. + """ + prompt_output = self.prompt_encoder( + input_points=input_points, + input_labels=input_labels, + input_boxes=input_boxes, + input_masks=input_masks, + ) + return prompt_output + + @merge_with_config_defaults + @capture_outputs + @auto_docstring + def forward( + self, + pixel_values: torch.FloatTensor | None = None, + input_points: torch.FloatTensor | None = None, + input_labels: torch.LongTensor | None = None, + input_boxes: torch.FloatTensor | None = None, + input_masks: torch.LongTensor | None = None, + image_embeddings: torch.FloatTensor | None = None, + multimask_output: bool = True, + hq_token_only: bool = False, + attention_similarity: torch.FloatTensor | None = None, + target_embedding: torch.FloatTensor | None = None, + intermediate_embeddings: list[torch.FloatTensor] | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> list[dict[str, torch.Tensor]]: + r""" + input_points (`torch.FloatTensor` of shape `(batch_size, num_points, 2)`): + Input 2D spatial points, this is used by the prompt encoder to encode the prompt. Generally yields to much + better results. The points can be obtained by passing a list of list of list to the processor that will + create corresponding `torch` tensors of dimension 4. The first dimension is the image batch size, the + second dimension is the point batch size (i.e. how many segmentation masks do we want the model to predict + per input point), the third dimension is the number of points per segmentation mask (it is possible to pass + multiple points for a single mask), and the last dimension is the x (vertical) and y (horizontal) + coordinates of the point. If a different number of points is passed either for each image, or for each + mask, the processor will create "PAD" points that will correspond to the (0, 0) coordinate, and the + computation of the embedding will be skipped for these points using the labels. + input_labels (`torch.LongTensor` of shape `(batch_size, point_batch_size, num_points)`): + Input labels for the points, this is used by the prompt encoder to encode the prompt. According to the + official implementation, there are 3 types of labels + + - `1`: the point is a point that contains the object of interest + - `0`: the point is a point that does not contain the object of interest + - `-1`: the point corresponds to the background + + We added the label: + + - `-10`: the point is a padding point, thus should be ignored by the prompt encoder + + The padding labels should be automatically done by the processor. + input_boxes (`torch.FloatTensor` of shape `(batch_size, num_boxes, 4)`): + Input boxes for the points, this is used by the prompt encoder to encode the prompt. Generally yields to + much better generated masks. The boxes can be obtained by passing a list of list of list to the processor, + that will generate a `torch` tensor, with each dimension corresponding respectively to the image batch + size, the number of boxes per image and the coordinates of the top left and bottom right point of the box. + In the order (`x1`, `y1`, `x2`, `y2`): + + - `x1`: the x coordinate of the top left point of the input box + - `y1`: the y coordinate of the top left point of the input box + - `x2`: the x coordinate of the bottom right point of the input box + - `y2`: the y coordinate of the bottom right point of the input box + input_masks (`torch.FloatTensor` of shape `(batch_size, image_size, image_size)`): + SAM_HQ model also accepts segmentation masks as input. The mask will be embedded by the prompt encoder to + generate a corresponding embedding, that will be fed later on to the mask decoder. These masks needs to be + manually fed by the user, and they need to be of shape (`batch_size`, `image_size`, `image_size`). + image_embeddings (`torch.FloatTensor` of shape `(batch_size, output_channels, window_size, window_size)`): + Image embeddings, this is used by the mask decder to generate masks and iou scores. For more memory + efficient computation, users can first retrieve the image embeddings using the `get_image_embeddings` + method, and then feed them to the `forward` method instead of feeding the `pixel_values`. + multimask_output (`bool`, *optional*): + In the original implementation and paper, the model always outputs 3 masks per image (or per point / per + bounding box if relevant). However, it is possible to just output a single mask, that corresponds to the + "best" mask, by specifying `multimask_output=False`. + hq_token_only (`bool`, *optional*, defaults to `False`): + Whether to use only the HQ token path for mask generation. When False, combines both standard and HQ paths. + This is specific to SAM-HQ's architecture. + attention_similarity (`torch.FloatTensor`, *optional*): + Attention similarity tensor, to be provided to the mask decoder for target-guided attention in case the + model is used for personalization as introduced in [PerSAM](https://huggingface.co/papers/2305.03048). + target_embedding (`torch.FloatTensor`, *optional*): + Embedding of the target concept, to be provided to the mask decoder for target-semantic prompting in case + the model is used for personalization as introduced in [PerSAM](https://huggingface.co/papers/2305.03048). + intermediate_embeddings (`List[torch.FloatTensor]`, *optional*): + Intermediate embeddings from vision encoder's non-windowed blocks, used by SAM-HQ for enhanced mask quality. + Required when providing pre-computed image_embeddings instead of pixel_values. + + Example: + + ```python + >>> from PIL import Image + >>> import httpx + >>> from io import BytesIO + >>> from transformers import AutoModel, AutoProcessor + + >>> model = AutoModel.from_pretrained("sushmanth/sam_hq_vit_b") + >>> processor = AutoProcessor.from_pretrained("sushmanth/sam_hq_vit_b") + + >>> url = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/model_doc/sam-car.png" + >>> with httpx.stream("GET", url) as response: + ... image = Image.open(BytesIO(response.read())).convert("RGB") + >>> input_points = [[[400, 650]]] # 2D location of a window on the car + >>> inputs = processor(images=image, input_points=input_points, return_tensors="pt") + + >>> # Get high-quality segmentation mask + >>> outputs = model(**inputs) + + >>> # For high-quality mask only + >>> outputs = model(**inputs, hq_token_only=True) + + >>> # Postprocess masks + >>> masks = processor.post_process_masks( + ... outputs.pred_masks, inputs["original_sizes"], inputs["reshaped_input_sizes"] + ... ) + ``` + """ + if pixel_values is None and image_embeddings is None: + raise ValueError("Either pixel_values or image_embeddings must be provided.") + + if pixel_values is not None and image_embeddings is not None: + raise ValueError("Only one of pixel_values and image_embeddings can be provided.") + + if input_points is not None and len(input_points.shape) != 4: + raise ValueError( + "The input_points must be a 4D tensor. Of shape `batch_size`, `point_batch_size`, `nb_points_per_image`, `2`." + f" got {input_points.shape}." + ) + + if input_boxes is not None and len(input_boxes.shape) != 3: + raise ValueError( + "The input_boxes must be a 3D tensor. Of shape `batch_size`, `nb_boxes`, `4`." + f" got {input_boxes.shape}." + ) + + # Add validation for point and box batch sizes + if input_points is not None and input_boxes is not None: + point_batch_size = input_points.shape[1] + box_batch_size = input_boxes.shape[1] + if point_batch_size != box_batch_size: + raise ValueError( + f"You should provide as many bounding boxes as input points per box. Got {point_batch_size} and {box_batch_size}." + ) + + image_positional_embeddings = self.get_image_wide_positional_embeddings() + # repeat with batch size + batch_size = pixel_values.shape[0] if pixel_values is not None else image_embeddings.shape[0] + image_positional_embeddings = image_positional_embeddings.repeat(batch_size, 1, 1, 1) + + if pixel_values is not None: + vision_outputs = self.vision_encoder(pixel_values, **kwargs) + image_embeddings = vision_outputs.last_hidden_state + intermediate_embeddings = vision_outputs.intermediate_embeddings + if input_points is not None and input_labels is None: + input_labels = torch.ones_like(input_points[:, :, :, 0], dtype=torch.int, device=input_points.device) + + sparse_embeddings, dense_embeddings = self.prompt_encoder( + input_points=input_points, + input_labels=input_labels, + input_boxes=input_boxes, + input_masks=input_masks, + ) + + # Predict masks + mask_decoder_output = self.mask_decoder( + image_embeddings=image_embeddings, + image_positional_embeddings=image_positional_embeddings, + sparse_prompt_embeddings=sparse_embeddings, + dense_prompt_embeddings=dense_embeddings, + multimask_output=multimask_output, + hq_token_only=hq_token_only, + intermediate_embeddings=intermediate_embeddings, + attention_similarity=attention_similarity, + target_embedding=target_embedding, + ) + return SamHQImageSegmentationOutput( + iou_scores=mask_decoder_output[1], + pred_masks=mask_decoder_output[0], + vision_hidden_states=vision_outputs.hidden_states if pixel_values is not None else None, + vision_attentions=vision_outputs.attentions if pixel_values is not None else None, + ) + + +__all__ = ["SamHQModel", "SamHQPreTrainedModel", "SamHQVisionModel"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam_hq/modular_sam_hq.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam_hq/modular_sam_hq.py new file mode 100644 index 0000000000000000000000000000000000000000..e14627b71683122a03d1ebed83bd3c21474509ad --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam_hq/modular_sam_hq.py @@ -0,0 +1,646 @@ +# Copyright 2025 Google Inc. HuggingFace Inc. team. All rights reserved. +# +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from dataclasses import dataclass + +import torch +from torch import nn + +from ...processing_utils import Unpack +from ...utils import auto_docstring, logging +from ...utils.generic import ModelOutput, TransformersKwargs, merge_with_config_defaults +from ...utils.output_capturing import capture_outputs +from ..sam.configuration_sam import SamConfig, SamMaskDecoderConfig, SamPromptEncoderConfig, SamVisionConfig +from ..sam.modeling_sam import ( + SamFeedForward, + SamImageSegmentationOutput, + SamLayerNorm, + SamModel, + SamPreTrainedModel, + SamTwoWayTransformer, + SamVisionAttention, + SamVisionEncoder, + SamVisionEncoderOutput, + SamVisionLayer, + SamVisionModel, +) + + +logger = logging.get_logger(__name__) + + +class SamHQPromptEncoderConfig(SamPromptEncoderConfig): + r""" + This is the configuration class to store the configuration of a [`SamHQPromptEncoderModel`].The [`SamHQPromptEncoderModel`] + module is used to encode the input 2D points and bounding boxes. Instantiating a configuration defaults will yield a + similar configuration to that of the SAM_HQ model. The configuration is used to store the configuration of the model. + [Uminosachi/sam-hq](https://huggingface.co/Uminosachi/sam-hq) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model's output.Read the documentation from + [`PreTrainedConfig`] for more information. + + Args: + hidden_size (`int`, *optional*, defaults to 256): + Dimensionality of the hidden states. + image_size (`int`, *optional*, defaults to 1024): + The expected output resolution of the image. + patch_size (`int`, *optional*, defaults to 16): + The size (resolution) of each patch. + mask_input_channels (`int`, *optional*, defaults to 16): + The number of channels to be fed to the `MaskDecoder` module. + num_point_embeddings (`int`, *optional*, defaults to 4): + The number of point embeddings to be used. + hidden_act (`str`, *optional*, defaults to `"gelu"`): + The non-linear activation function in the encoder and pooler. + """ + + +class SamHQVisionConfig(SamVisionConfig): + pass + + +class SamHQMaskDecoderConfig(SamMaskDecoderConfig): + r""" + This is the configuration class to store the configuration of a [`SamHQMaskDecoder`]. It is used to instantiate a SAM_HQ + mask decoder to the specified arguments, defining the model architecture. Instantiating a configuration defaults + will yield a similar configuration to that of the SAM_HQ-vit-h + [facebook/sam_hq-vit-huge](https://huggingface.co/facebook/sam_hq-vit-huge) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + hidden_size (`int`, *optional*, defaults to 256): + Dimensionality of the hidden states. + hidden_act (`str`, *optional*, defaults to `"relu"`): + The non-linear activation function used inside the `SamHQMaskDecoder` module. + mlp_dim (`int`, *optional*, defaults to 2048): + Dimensionality of the "intermediate" (i.e., feed-forward) layer in the Transformer encoder. + num_hidden_layers (`int`, *optional*, defaults to 2): + Number of hidden layers in the Transformer encoder. + num_attention_heads (`int`, *optional*, defaults to 8): + Number of attention heads for each attention layer in the Transformer encoder. + attention_downsample_rate (`int`, *optional*, defaults to 2): + The downsampling rate of the attention layer. + num_multimask_outputs (`int`, *optional*, defaults to 3): + The number of outputs from the `SamHQMaskDecoder` module. In the Segment Anything paper, this is set to 3. + iou_head_depth (`int`, *optional*, defaults to 3): + The number of layers in the IoU head module. + iou_head_hidden_dim (`int`, *optional*, defaults to 256): + The dimensionality of the hidden states in the IoU head module. + layer_norm_eps (`float`, *optional*, defaults to 1e-06): + The epsilon used by the layer normalization layers. + vit_dim (`int`, *optional*, defaults to 768): + Dimensionality of the Vision Transformer (ViT) used in the `SamHQMaskDecoder` module. + """ + + def __init__( + self, + vit_dim=768, + **super_kwargs, + ): + super().__init__(**super_kwargs) + self.vit_dim = vit_dim + + +class SamHQConfig(SamConfig): + r""" + [`SamHQConfig`] is the configuration class to store the configuration of a [`SamHQModel`]. It is used to instantiate a + SAM-HQ model according to the specified arguments, defining the vision model, prompt-encoder model and mask decoder + configs. Instantiating a configuration with the defaults will yield a similar configuration to that of the + SAM-HQ-ViT-H [sushmanth/sam_hq_vit_h](https://huggingface.co/sushmanth/sam_hq_vit_h) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + vision_config (Union[`dict`, `SamHQVisionConfig`], *optional*): + Dictionary of configuration options used to initialize [`SamHQVisionConfig`]. + prompt_encoder_config (Union[`dict`, `SamHQPromptEncoderConfig`], *optional*): + Dictionary of configuration options used to initialize [`SamHQPromptEncoderConfig`]. + mask_decoder_config (Union[`dict`, `SamHQMaskDecoderConfig`], *optional*): + Dictionary of configuration options used to initialize [`SamHQMaskDecoderConfig`]. + kwargs (*optional*): + Dictionary of keyword arguments. + """ + + +class SamHQVisionEncoderOutput(SamVisionEncoderOutput): + r""" + image_embeds (`torch.FloatTensor` of shape `(batch_size, output_dim)` *optional* returned when model is initialized with `with_projection=True`): + The image embeddings obtained by applying the projection layer to the pooler_output. + intermediate_embeddings (`list(torch.FloatTensor)`, *optional*): + A list of intermediate embeddings collected from certain blocks within the model, typically those without + windowed attention. Each element in the list is of shape `(batch_size, sequence_length, hidden_size)`. + This is specific to SAM-HQ and not present in base SAM. + """ + + intermediate_embeddings: list[torch.FloatTensor] | None = None + + +@dataclass +class SamHQMMaskDecoderOutputs(ModelOutput): + r""" + masks (`torch.FloatTensor` of shape `(batch_size, num_prompts, num_masks, height, width)`): + The predicted masks for the input image. The masks are of shape `(batch_size, num_prompts, num_masks, height, width)`. + iou_scores (`torch.FloatTensor` of shape `(batch_size, num_prompts, num_masks)`): + The predicted IoU scores for each mask. The scores are of shape `(batch_size, num_prompts, num_masks)`. + mask_decoder_attentions (`torch.FloatTensor`, *optional*): + The attention weights from the mask decoder, if `output_attentions=True` was passed during the forward pass. + This is specific to SAM-HQ and not present in base SAM. + """ + + masks: torch.FloatTensor + iou_scores: torch.FloatTensor | None = None + mask_decoder_attentions: torch.FloatTensor | None = None + + +class SamHQImageSegmentationOutput(SamImageSegmentationOutput): + pass + + +class SamHQVisionAttention(SamVisionAttention): + pass + + +class SamHQVisionLayer(SamVisionLayer): + pass + + +class SamHQPreTrainedModel(SamPreTrainedModel): + pass + + +class SamHQVisionEncoder(SamVisionEncoder, SamHQPreTrainedModel): + _can_record_outputs = { + "hidden_states": SamHQVisionLayer, + "attentions": SamHQVisionAttention, + } + + @merge_with_config_defaults + @capture_outputs(tie_last_hidden_states=False) + def forward( + self, pixel_values: torch.FloatTensor | None = None, **kwargs: Unpack[TransformersKwargs] + ) -> tuple | SamHQVisionEncoderOutput: + if pixel_values is None: + raise ValueError("You have to specify pixel_values") + + hidden_states = self.patch_embed(pixel_values) + if self.pos_embed is not None: + hidden_states = hidden_states + self.pos_embed + + intermediate_embeddings = [] + + for layer_module in self.layers: + hidden_states = layer_module(hidden_states) + + # Collect embeddings from non-windowed blocks + if hasattr(layer_module, "window_size") and layer_module.window_size == 0: + intermediate_embeddings.append(hidden_states) + + hidden_states = self.neck(hidden_states) + + return SamHQVisionEncoderOutput( + last_hidden_state=hidden_states, + intermediate_embeddings=intermediate_embeddings, + ) + + +class SamHQLayerNorm(SamLayerNorm): + pass + + +class SamHQTwoWayTransformer(SamTwoWayTransformer): + pass + + +class SamHQFeedForward(SamFeedForward): + pass + + +class SamHQMaskDecoder(nn.Module): + def __init__(self, config: SamHQMaskDecoderConfig): + super().__init__() + self.hidden_size = config.hidden_size + + self.num_multimask_outputs = config.num_multimask_outputs + self.num_mask_tokens = config.num_multimask_outputs + 1 + + self.iou_token = nn.Embedding(1, self.hidden_size) + self.mask_tokens = nn.Embedding(self.num_mask_tokens, self.hidden_size) + + self.transformer = SamHQTwoWayTransformer(config) + + self.upscale_conv1 = nn.ConvTranspose2d(self.hidden_size, self.hidden_size // 4, kernel_size=2, stride=2) + self.upscale_conv2 = nn.ConvTranspose2d(self.hidden_size // 4, self.hidden_size // 8, kernel_size=2, stride=2) + self.upscale_layer_norm = SamHQLayerNorm(self.hidden_size // 4, data_format="channels_first") + self.activation = nn.GELU() + + mlps_list = [] + for _ in range(self.num_mask_tokens): + mlps_list += [SamHQFeedForward(self.hidden_size, self.hidden_size, self.hidden_size // 8, 3)] + self.output_hypernetworks_mlps = nn.ModuleList(mlps_list) + + self.iou_prediction_head = SamHQFeedForward( + self.hidden_size, config.iou_head_hidden_dim, self.num_mask_tokens, config.iou_head_depth + ) + + self.hq_token = nn.Embedding(1, self.hidden_size) + self.hq_mask_mlp = SamHQFeedForward(self.hidden_size, self.hidden_size, self.hidden_size // 8, 3) + self.num_mask_tokens = self.num_mask_tokens + 1 + + # Compress ViT features + self.compress_vit_conv1 = nn.ConvTranspose2d(config.vit_dim, self.hidden_size, kernel_size=2, stride=2) + self.compress_vit_norm = SamHQLayerNorm(self.hidden_size, data_format="channels_first") + self.compress_vit_conv2 = nn.ConvTranspose2d(self.hidden_size, self.hidden_size // 8, kernel_size=2, stride=2) + + # Embedding encoder + self.encoder_conv1 = nn.ConvTranspose2d(self.hidden_size, self.hidden_size // 4, kernel_size=2, stride=2) + self.encoder_norm = SamHQLayerNorm(self.hidden_size // 4, data_format="channels_first") + self.encoder_conv2 = nn.ConvTranspose2d(self.hidden_size // 4, self.hidden_size // 8, kernel_size=2, stride=2) + + # Embedding mask feature + self.mask_conv1 = nn.Conv2d(self.hidden_size // 8, self.hidden_size // 4, kernel_size=3, stride=1, padding=1) + self.mask_norm = SamHQLayerNorm(self.hidden_size // 4, data_format="channels_first") + self.mask_conv2 = nn.Conv2d(self.hidden_size // 4, self.hidden_size // 8, kernel_size=3, stride=1, padding=1) + + def forward( + self, + image_embeddings: torch.Tensor, + image_positional_embeddings: torch.Tensor, + sparse_prompt_embeddings: torch.Tensor, + dense_prompt_embeddings: torch.Tensor, + multimask_output: bool, + hq_token_only: bool, + intermediate_embeddings: list[torch.Tensor] | None = None, + attention_similarity: torch.Tensor | None = None, + target_embedding: torch.Tensor | None = None, + ) -> SamHQMMaskDecoderOutputs: + """ + Predict high-quality masks given image and prompt embeddings. + + Args: + image_embeddings (`torch.Tensor`): + The embeddings from the image encoder. + image_positional_embedding (`torch.Tensor`): + Positional encoding with the shape of image_embeddings. + sparse_prompt_embeddings (`torch.Tensor`): + The embeddings of the points and boxes. + dense_prompt_embeddings (`torch.Tensor`): + The embeddings of the mask inputs. + multimask_output (bool): + Whether to return multiple masks or a single mask. + hq_token_only (bool): + Whether to use only the high-quality token output or combine with SAM output. + intermediate_embeddings (`torch.Tensor`): + Intermediate embeddings from the vision encoder for feature fusion. + attention_similarity (`torch.Tensor`, *optional*): + Optional tensor for attention similarity computation. + target_embedding (`torch.Tensor`, *optional*): + Optional target embedding for transformer processing. + + Returns: + `Tuple[torch.Tensor, torch.Tensor, Optional[torch.Tensor]]`: A tuple of tensors containing: + - A tensor of shape `(batch_size, num_prompts, num_masks, height, width)` containing the output masks. + - A tensor of shape `(batch_size, num_prompts, num_masks)` containing the iou predictions for each mask. + - (Optional) A tuple containing attention tensors if output_attentions is True. + """ + batch_size, num_channels, height, width = image_embeddings.shape + point_batch_size = sparse_prompt_embeddings.shape[1] if sparse_prompt_embeddings is not None else 1 + + has_intermediate = intermediate_embeddings is not None and len(intermediate_embeddings) > 0 + + if has_intermediate: + vit_features = intermediate_embeddings[0].permute(0, 3, 1, 2).contiguous() + + embed_encode = self.encoder_conv1(image_embeddings) + embed_encode = self.activation(self.encoder_norm(embed_encode)) + embed_encode = self.encoder_conv2(embed_encode) + + if has_intermediate: + compressed_vit_features = self.compress_vit_conv1(vit_features) + compressed_vit_features = self.activation(self.compress_vit_norm(compressed_vit_features)) + compressed_vit_features = self.compress_vit_conv2(compressed_vit_features) + + hq_features = embed_encode + compressed_vit_features + else: + hq_features = embed_encode + + output_tokens = torch.cat([self.iou_token.weight, self.mask_tokens.weight, self.hq_token.weight], dim=0) + output_tokens = output_tokens.repeat(batch_size, point_batch_size, 1, 1) + + if sparse_prompt_embeddings is not None: + tokens = torch.cat([output_tokens, sparse_prompt_embeddings], dim=2) + else: + tokens = output_tokens + point_embeddings = tokens.to(self.iou_token.weight.dtype) + image_embeddings = image_embeddings + dense_prompt_embeddings + image_embeddings = image_embeddings.repeat_interleave(point_batch_size, 0) + image_positional_embeddings = image_positional_embeddings.repeat_interleave(point_batch_size, 0) + + point_embedding, iou_token_out = self.transformer( + point_embeddings=point_embeddings, + image_embeddings=image_embeddings, + image_positional_embeddings=image_positional_embeddings, + attention_similarity=attention_similarity, + target_embedding=target_embedding, + ) + iou_token_out = point_embedding[:, :, 0, :] + mask_tokens_out = point_embedding[:, :, 1 : (1 + self.num_mask_tokens), :] + + image_embeddings = image_embeddings.transpose(2, 3).reshape( + batch_size * point_batch_size, num_channels, height, width + ) + + upscaled_embedding = self.upscale_conv1(image_embeddings) + upscaled_embedding = self.activation(self.upscale_layer_norm(upscaled_embedding)) + upscaled_embedding = self.activation(self.upscale_conv2(upscaled_embedding)) + + upscaled_embedding_hq = self.mask_conv1(upscaled_embedding) + upscaled_embedding_hq = self.activation(self.mask_norm(upscaled_embedding_hq)) + upscaled_embedding_hq = self.mask_conv2(upscaled_embedding_hq) + + if hq_features.shape[0] == 1: + hq_features = hq_features.repeat(batch_size * point_batch_size, 1, 1, 1) + elif hq_features.shape[0] == batch_size and batch_size * point_batch_size != batch_size: + hq_features = hq_features.repeat_interleave(point_batch_size, 0) + upscaled_embedding_hq = upscaled_embedding_hq + hq_features + + hyper_in_list = [] + for mask_token_index in range(self.num_mask_tokens): + if mask_token_index < self.num_mask_tokens - 1: + current_mlp = self.output_hypernetworks_mlps[mask_token_index] + else: + current_mlp = self.hq_mask_mlp + hyper_in_list += [current_mlp(mask_tokens_out[:, :, mask_token_index, :])] + + hyper_in = torch.stack(hyper_in_list, dim=2) + _, num_channels, height, width = upscaled_embedding.shape + upscaled_embedding = upscaled_embedding.reshape(batch_size, point_batch_size, num_channels, height * width) + upscaled_embedding_hq = upscaled_embedding_hq.reshape( + batch_size, point_batch_size, num_channels, height * width + ) + + masks_sam = (hyper_in[:, :, : self.num_mask_tokens - 1] @ upscaled_embedding).reshape( + batch_size, point_batch_size, -1, height, width + ) + masks_hq = (hyper_in[:, :, self.num_mask_tokens - 1 :] @ upscaled_embedding_hq).reshape( + batch_size, point_batch_size, -1, height, width + ) + masks = torch.cat([masks_sam, masks_hq], dim=2) + + iou_pred = self.iou_prediction_head(iou_token_out) + + if multimask_output: + mask_slice = slice(1, self.num_mask_tokens - 1) + iou_pred = iou_pred[:, :, mask_slice] + # Sort the IoU scores in descending order and get indices + iou_pred_sorted, sort_indices = torch.sort(iou_pred, dim=2, descending=True) + # Reorder the masks according to sorted scores + masks_sam = masks[:, :, mask_slice, :, :] + masks_sam = torch.gather( + masks_sam, + 2, + sort_indices[..., None, None].expand(-1, -1, -1, masks_sam.shape[3], masks_sam.shape[4]), + ) + # Update iou_pred with sorted scores + iou_pred = iou_pred_sorted + else: + mask_slice = slice(0, 1) + iou_pred = iou_pred[:, :, mask_slice] + masks_sam = masks[:, :, mask_slice, :, :] + + masks_hq = masks[:, :, slice(self.num_mask_tokens - 1, self.num_mask_tokens), :, :] + if hq_token_only: + masks = masks_hq + else: + masks = masks_sam + masks_hq + + return masks, iou_pred + + +class SamHQVisionModel(SamVisionModel): + pass + + +@auto_docstring( + custom_intro=""" + Segment Anything Model HQ (SAM-HQ) for generating masks, given an input image and optional 2D location and bounding boxes. + """ +) +class SamHQModel(SamModel): + def __init__(self, config): + super().__init__(config) + self.vision_encoder = SamHQVisionEncoder(config.vision_config) + + self.mask_decoder = SamHQMaskDecoder(config.mask_decoder_config) + + self.post_init() + + @torch.no_grad() + def get_image_embeddings( + self, + pixel_values, + ): + r""" + Returns the image embeddings by passing the pixel values through the vision encoder. + + Args: + pixel_values (`torch.FloatTensor` of shape `(batch_size, num_channels, height, width)`): + Input pixel values + """ + vision_output = self.vision_encoder(pixel_values=pixel_values) + image_embeddings = vision_output[0] + intermediate_embeddings = vision_output[1] + return image_embeddings, intermediate_embeddings + + def forward( + self, + pixel_values: torch.FloatTensor | None = None, + input_points: torch.FloatTensor | None = None, + input_labels: torch.LongTensor | None = None, + input_boxes: torch.FloatTensor | None = None, + input_masks: torch.LongTensor | None = None, + image_embeddings: torch.FloatTensor | None = None, + multimask_output: bool = True, + hq_token_only: bool = False, + attention_similarity: torch.FloatTensor | None = None, + target_embedding: torch.FloatTensor | None = None, + intermediate_embeddings: list[torch.FloatTensor] | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> list[dict[str, torch.Tensor]]: + r""" + input_points (`torch.FloatTensor` of shape `(batch_size, num_points, 2)`): + Input 2D spatial points, this is used by the prompt encoder to encode the prompt. Generally yields to much + better results. The points can be obtained by passing a list of list of list to the processor that will + create corresponding `torch` tensors of dimension 4. The first dimension is the image batch size, the + second dimension is the point batch size (i.e. how many segmentation masks do we want the model to predict + per input point), the third dimension is the number of points per segmentation mask (it is possible to pass + multiple points for a single mask), and the last dimension is the x (vertical) and y (horizontal) + coordinates of the point. If a different number of points is passed either for each image, or for each + mask, the processor will create "PAD" points that will correspond to the (0, 0) coordinate, and the + computation of the embedding will be skipped for these points using the labels. + input_labels (`torch.LongTensor` of shape `(batch_size, point_batch_size, num_points)`): + Input labels for the points, this is used by the prompt encoder to encode the prompt. According to the + official implementation, there are 3 types of labels + + - `1`: the point is a point that contains the object of interest + - `0`: the point is a point that does not contain the object of interest + - `-1`: the point corresponds to the background + + We added the label: + + - `-10`: the point is a padding point, thus should be ignored by the prompt encoder + + The padding labels should be automatically done by the processor. + input_boxes (`torch.FloatTensor` of shape `(batch_size, num_boxes, 4)`): + Input boxes for the points, this is used by the prompt encoder to encode the prompt. Generally yields to + much better generated masks. The boxes can be obtained by passing a list of list of list to the processor, + that will generate a `torch` tensor, with each dimension corresponding respectively to the image batch + size, the number of boxes per image and the coordinates of the top left and bottom right point of the box. + In the order (`x1`, `y1`, `x2`, `y2`): + + - `x1`: the x coordinate of the top left point of the input box + - `y1`: the y coordinate of the top left point of the input box + - `x2`: the x coordinate of the bottom right point of the input box + - `y2`: the y coordinate of the bottom right point of the input box + input_masks (`torch.FloatTensor` of shape `(batch_size, image_size, image_size)`): + SAM_HQ model also accepts segmentation masks as input. The mask will be embedded by the prompt encoder to + generate a corresponding embedding, that will be fed later on to the mask decoder. These masks needs to be + manually fed by the user, and they need to be of shape (`batch_size`, `image_size`, `image_size`). + image_embeddings (`torch.FloatTensor` of shape `(batch_size, output_channels, window_size, window_size)`): + Image embeddings, this is used by the mask decder to generate masks and iou scores. For more memory + efficient computation, users can first retrieve the image embeddings using the `get_image_embeddings` + method, and then feed them to the `forward` method instead of feeding the `pixel_values`. + multimask_output (`bool`, *optional*): + In the original implementation and paper, the model always outputs 3 masks per image (or per point / per + bounding box if relevant). However, it is possible to just output a single mask, that corresponds to the + "best" mask, by specifying `multimask_output=False`. + hq_token_only (`bool`, *optional*, defaults to `False`): + Whether to use only the HQ token path for mask generation. When False, combines both standard and HQ paths. + This is specific to SAM-HQ's architecture. + attention_similarity (`torch.FloatTensor`, *optional*): + Attention similarity tensor, to be provided to the mask decoder for target-guided attention in case the + model is used for personalization as introduced in [PerSAM](https://huggingface.co/papers/2305.03048). + target_embedding (`torch.FloatTensor`, *optional*): + Embedding of the target concept, to be provided to the mask decoder for target-semantic prompting in case + the model is used for personalization as introduced in [PerSAM](https://huggingface.co/papers/2305.03048). + intermediate_embeddings (`List[torch.FloatTensor]`, *optional*): + Intermediate embeddings from vision encoder's non-windowed blocks, used by SAM-HQ for enhanced mask quality. + Required when providing pre-computed image_embeddings instead of pixel_values. + + Example: + + ```python + >>> from PIL import Image + >>> import httpx + >>> from io import BytesIO + >>> from transformers import AutoModel, AutoProcessor + + >>> model = AutoModel.from_pretrained("sushmanth/sam_hq_vit_b") + >>> processor = AutoProcessor.from_pretrained("sushmanth/sam_hq_vit_b") + + >>> url = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/model_doc/sam-car.png" + >>> with httpx.stream("GET", url) as response: + ... image = Image.open(BytesIO(response.read())).convert("RGB") + >>> input_points = [[[400, 650]]] # 2D location of a window on the car + >>> inputs = processor(images=image, input_points=input_points, return_tensors="pt") + + >>> # Get high-quality segmentation mask + >>> outputs = model(**inputs) + + >>> # For high-quality mask only + >>> outputs = model(**inputs, hq_token_only=True) + + >>> # Postprocess masks + >>> masks = processor.post_process_masks( + ... outputs.pred_masks, inputs["original_sizes"], inputs["reshaped_input_sizes"] + ... ) + ``` + """ + if pixel_values is None and image_embeddings is None: + raise ValueError("Either pixel_values or image_embeddings must be provided.") + + if pixel_values is not None and image_embeddings is not None: + raise ValueError("Only one of pixel_values and image_embeddings can be provided.") + + if input_points is not None and len(input_points.shape) != 4: + raise ValueError( + "The input_points must be a 4D tensor. Of shape `batch_size`, `point_batch_size`, `nb_points_per_image`, `2`." + f" got {input_points.shape}." + ) + + if input_boxes is not None and len(input_boxes.shape) != 3: + raise ValueError( + "The input_boxes must be a 3D tensor. Of shape `batch_size`, `nb_boxes`, `4`." + f" got {input_boxes.shape}." + ) + + # Add validation for point and box batch sizes + if input_points is not None and input_boxes is not None: + point_batch_size = input_points.shape[1] + box_batch_size = input_boxes.shape[1] + if point_batch_size != box_batch_size: + raise ValueError( + f"You should provide as many bounding boxes as input points per box. Got {point_batch_size} and {box_batch_size}." + ) + + image_positional_embeddings = self.get_image_wide_positional_embeddings() + # repeat with batch size + batch_size = pixel_values.shape[0] if pixel_values is not None else image_embeddings.shape[0] + image_positional_embeddings = image_positional_embeddings.repeat(batch_size, 1, 1, 1) + + if pixel_values is not None: + vision_outputs = self.vision_encoder(pixel_values, **kwargs) + image_embeddings = vision_outputs.last_hidden_state + intermediate_embeddings = vision_outputs.intermediate_embeddings + if input_points is not None and input_labels is None: + input_labels = torch.ones_like(input_points[:, :, :, 0], dtype=torch.int, device=input_points.device) + + sparse_embeddings, dense_embeddings = self.prompt_encoder( + input_points=input_points, + input_labels=input_labels, + input_boxes=input_boxes, + input_masks=input_masks, + ) + + # Predict masks + mask_decoder_output = self.mask_decoder( + image_embeddings=image_embeddings, + image_positional_embeddings=image_positional_embeddings, + sparse_prompt_embeddings=sparse_embeddings, + dense_prompt_embeddings=dense_embeddings, + multimask_output=multimask_output, + hq_token_only=hq_token_only, + intermediate_embeddings=intermediate_embeddings, + attention_similarity=attention_similarity, + target_embedding=target_embedding, + ) + return SamHQImageSegmentationOutput( + iou_scores=mask_decoder_output[1], + pred_masks=mask_decoder_output[0], + vision_hidden_states=vision_outputs.hidden_states if pixel_values is not None else None, + vision_attentions=vision_outputs.attentions if pixel_values is not None else None, + ) + + +__all__ = [ + "SamHQVisionConfig", + "SamHQMaskDecoderConfig", + "SamHQPromptEncoderConfig", + "SamHQConfig", + "SamHQModel", + "SamHQPreTrainedModel", + "SamHQVisionModel", +] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam_hq/processing_sam_hq.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam_hq/processing_sam_hq.py new file mode 100644 index 0000000000000000000000000000000000000000..8bd9d814a9759b731bc9fa23437ced568122b9b9 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sam_hq/processing_sam_hq.py @@ -0,0 +1,327 @@ +# Copyright 2025 The HuggingFace Inc. team. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +""" +Processor class for SAMHQ. +""" + +from copy import deepcopy +from typing import Union + +import numpy as np + +from ...feature_extraction_utils import BatchFeature +from ...image_utils import ImageInput +from ...processing_utils import ImagesKwargs, ProcessingKwargs, ProcessorMixin, Unpack +from ...utils import auto_docstring, is_torch_available + + +if is_torch_available(): + import torch + +NestedList = list[Union[float | int | None, "NestedList"]] + + +class SamHQImagesKwargs(ImagesKwargs, total=False): + """ + segmentation_maps (`ImageInput`, *optional*): + Ground truth segmentation maps to process alongside the input images. These maps are used for training + or evaluation purposes and are resized and normalized to match the processed image dimensions. + input_points (`NestedList`, *optional*): + Input points for prompt-based segmentation. Should be a nested list with structure + `[image_level, object_level, point_level, [x, y]]` where each point is specified as `[x, y]` coordinates + in the original image space. Points are normalized to the target image size before being passed to the model. + input_labels (`NestedList`, *optional*): + Labels for the input points, indicating whether each point is a foreground (1) or background (0) point. + Should be a nested list with structure `[image_level, object_level, point_level]`. Must have the same + structure as `input_points` (excluding the coordinate dimension). + input_boxes (`NestedList`, *optional*): + Bounding boxes for prompt-based segmentation. Should be a nested list with structure + `[image_level, box_level, [x1, y1, x2, y2]]` where each box is specified as `[x1, y1, x2, y2]` coordinates + in the original image space. Boxes are normalized to the target image size before being passed to the model. + point_pad_value (`int`, *optional*, defaults to `None`): + The value used for padding input points when batching sequences of different lengths. This value marks + padded positions and is preserved during coordinate normalization to distinguish real points from padding. + If `None`, the default pad value from the processor configuration is used. + mask_size (`dict[str, int]`, *optional*): + Dictionary specifying the target mask size with keys `"height"` and `"width"`. This determines the + resolution of the output segmentation masks generated by the model. + mask_pad_size (`dict[str, int]`, *optional*): + Dictionary specifying the padding size for masks with keys `"height"` and `"width"`. This is used when + batching masks of different sizes to ensure consistent dimensions. + """ + + segmentation_maps: ImageInput | None + input_points: "NestedList | torch.Tensor | None" + input_labels: "NestedList | int | torch.Tensor | None" + input_boxes: "NestedList | torch.Tensor | None" + point_pad_value: int | None + mask_size: dict[str, int] + mask_pad_size: dict[str, int] + + +class SamHQProcessorKwargs(ProcessingKwargs, total=False): + images_kwargs: SamHQImagesKwargs + _defaults = { + "images_kwargs": { + "point_pad_value": None, + } + } + + +@auto_docstring +class SamHQProcessor(ProcessorMixin): + def __init__(self, image_processor): + super().__init__(image_processor) + # Ensure image_processor is properly initialized + if not hasattr(self, "image_processor"): + raise ValueError("image_processor was not properly initialized") + if not hasattr(self.image_processor, "size"): + raise ValueError("image_processor.size is not set") + self.target_size = self.image_processor.size["longest_edge"] + + @auto_docstring + def __call__( + self, + images: ImageInput | None = None, + **kwargs: Unpack[SamHQProcessorKwargs], + ) -> BatchFeature: + output_kwargs = self._merge_kwargs( + SamHQProcessorKwargs, + tokenizer_init_kwargs={}, + **kwargs, + ) + + input_points = output_kwargs["images_kwargs"].pop("input_points", None) + input_labels = output_kwargs["images_kwargs"].pop("input_labels", None) + input_boxes = output_kwargs["images_kwargs"].pop("input_boxes", None) + point_pad_value = output_kwargs["images_kwargs"].pop("point_pad_value", None) + + encoding_image_processor = self.image_processor( + images, + **output_kwargs["images_kwargs"], + ) + + original_sizes = encoding_image_processor["original_sizes"] + + if hasattr(original_sizes, "numpy"): + original_sizes = original_sizes.numpy() + + input_points, input_labels, input_boxes = self._check_and_preprocess_points( + input_points=input_points, + input_labels=input_labels, + input_boxes=input_boxes, + ) + + encoding_image_processor = self._normalize_and_convert( + encoding_image_processor, + original_sizes, + input_points=input_points, + input_labels=input_labels, + input_boxes=input_boxes, + return_tensors=output_kwargs["images_kwargs"].get("return_tensors"), + point_pad_value=point_pad_value, + ) + + return encoding_image_processor + + def _normalize_and_convert( + self, + encoding_image_processor, + original_sizes, + input_points=None, + input_labels=None, + input_boxes=None, + return_tensors="pt", + point_pad_value=-10, + ): + """ + Normalize and convert the image processor output to the expected format. + """ + # Process input points + if input_points is not None: + input_points = self._normalize_batch_coordinates(input_points, original_sizes) + + if not all(point.shape == input_points[0].shape for point in input_points): + if input_labels is not None: + input_points, input_labels = self._pad_points_and_labels( + input_points, input_labels, point_pad_value + ) + + input_points = np.array(input_points) + + # Process input labels + if input_labels is not None: + input_labels = np.array(input_labels) + + # Process input boxes + if input_boxes is not None: + input_boxes = self._normalize_batch_coordinates(input_boxes, original_sizes, is_bounding_box=True) + input_boxes = np.array(input_boxes) + + # Update processor with converted inputs + if input_boxes is not None: + encoding_image_processor["input_boxes"] = self._to_tensor(input_boxes, 3, return_tensors) + if input_points is not None: + encoding_image_processor["input_points"] = self._to_tensor(input_points, 4, return_tensors) + if input_labels is not None: + encoding_image_processor["input_labels"] = self._to_tensor(input_labels, 3, return_tensors) + + return encoding_image_processor + + def _pad_points_and_labels(self, input_points, input_labels, point_pad_value): + r""" + The method pads the 2D points and labels to the maximum number of points in the batch. + """ + expected_nb_points = max(point.shape[0] for point in input_points) + processed_input_points = [] + for i, point in enumerate(input_points): + if point.shape[0] != expected_nb_points: + point = np.concatenate( + [point, np.zeros((expected_nb_points - point.shape[0], 2)) + point_pad_value], axis=0 + ) + input_labels[i] = np.append(input_labels[i], [point_pad_value]) + processed_input_points.append(point) + input_points = processed_input_points + return input_points, input_labels + + def _normalize_coordinates( + self, target_size: int, coords: np.ndarray, original_size, is_bounding_box=False + ) -> np.ndarray: + """ + Expects a numpy array of length 2 in the final dimension. Requires the original image size in (H,W) format. + """ + old_h, old_w = original_size + new_h, new_w = self.image_processor._get_preprocess_shape(original_size, longest_edge=target_size) + coords = deepcopy(coords).astype(float) + + if is_bounding_box: + coords = coords.reshape(-1, 2, 2) + + coords[..., 0] = coords[..., 0] * (new_w / old_w) + coords[..., 1] = coords[..., 1] * (new_h / old_h) + + if is_bounding_box: + coords = coords.reshape(-1, 4) + + return coords + + def _preprocess_input(self, inputs, error_message, expected_nesting=1, dtype=None): + """ + Preprocess input by converting torch tensors to numpy arrays and validating structure. + + Args: + inputs: The input to process + error_message: Error message if validation fails + expected_nesting: Expected nesting level (1 for points/labels, 2 for boxes) + dtype: Optional data type for numpy array conversion + + Returns: + Processed input as list of numpy arrays or None + """ + if inputs is None: + return None + + # Convert torch tensor to list if applicable + if hasattr(inputs, "numpy"): + inputs = inputs.numpy().tolist() + + # Validate structure based on expected nesting + valid = isinstance(inputs, list) + current = inputs + + for _ in range(expected_nesting): + if not valid or not current: + break + valid = valid and isinstance(current[0], list) + current = current[0] if current else None + + if not valid: + raise ValueError(error_message) + + # Convert to numpy arrays + return [np.array(item, dtype=dtype) for item in inputs] + + def _check_and_preprocess_points( + self, + input_points=None, + input_labels=None, + input_boxes=None, + ): + r""" + Check and preprocesses the 2D points, labels and bounding boxes. It checks if the input is valid and if they + are, it converts the coordinates of the points and bounding boxes. If a user passes directly a `torch.Tensor`, + it is converted to a `numpy.ndarray` and then to a `list`. + """ + # Process each input type + input_points = self._preprocess_input(input_points, "Input points must be a list of list of floating points.") + + input_labels = self._preprocess_input(input_labels, "Input labels must be a list of list integers.") + + input_boxes = self._preprocess_input( + input_boxes, + "Input boxes must be a list of list of list of floating points.", + expected_nesting=2, + dtype=np.float32, + ) + + return input_points, input_labels, input_boxes + + @property + def model_input_names(self): + image_processor_input_names = self.image_processor.model_input_names + return list(image_processor_input_names + ["original_sizes", "reshaped_input_sizes"]) + + def post_process_masks(self, *args, **kwargs): + return self.image_processor.post_process_masks(*args, **kwargs) + + def _to_tensor(self, array, min_dim, return_tensors): + """ + Convert numpy array to tensor and ensure proper dimensionality. + Args: + array: The numpy array to convert + min_dim: The minimum number of dimensions the result should have + return_tensors: The type of tensors to return (e.g., "pt" for PyTorch tensors) + Returns: + The converted array or tensor with proper dimensions + """ + if return_tensors == "pt": + array = torch.from_numpy(array) + return array.unsqueeze(1) if array.ndim < min_dim else array + return array + + def _normalize_batch_coordinates(self, inputs, original_sizes, is_bounding_box=False): + """ + Normalize coordinates based on original sizes. + Args: + inputs: List of coordinate arrays + original_sizes: Original sizes of the images + is_bounding_box: Whether inputs are bounding boxes + Returns: + Normalized coordinates as list + """ + if len(original_sizes) != len(inputs): + # Use first original size for all inputs + return [ + self._normalize_coordinates(self.target_size, item, original_sizes[0], is_bounding_box=is_bounding_box) + for item in inputs + ] + else: + # Use paired original sizes for each input + return [ + self._normalize_coordinates(self.target_size, item, size, is_bounding_box=is_bounding_box) + for item, size in zip(inputs, original_sizes) + ] + + +__all__ = ["SamHQProcessor"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/seamless_m4t/__init__.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/seamless_m4t/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..27c08de501c141e44e7e101b79f228e826396ff7 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/seamless_m4t/__init__.py @@ -0,0 +1,30 @@ +# Copyright 2024 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from typing import TYPE_CHECKING + +from ...utils import _LazyModule +from ...utils.import_utils import define_import_structure + + +if TYPE_CHECKING: + from .configuration_seamless_m4t import * + from .feature_extraction_seamless_m4t import * + from .modeling_seamless_m4t import * + from .processing_seamless_m4t import * + from .tokenization_seamless_m4t import * +else: + import sys + + _file = globals()["__file__"] + sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__) diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/seamless_m4t/configuration_seamless_m4t.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/seamless_m4t/configuration_seamless_m4t.py new file mode 100644 index 0000000000000000000000000000000000000000..0168311c9ba135826f5ab56d1a3f05a070f79264 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/seamless_m4t/configuration_seamless_m4t.py @@ -0,0 +1,414 @@ +# Copyright 2023 The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""SeamlessM4T model configuration""" + +from ...configuration_utils import PreTrainedConfig +from ...utils import logging + + +logger = logging.get_logger(__name__) + + +class SeamlessM4TConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`~SeamlessM4TModel`]. It is used to instantiate an + SeamlessM4T model according to the specified arguments, defining the model architecture. Instantiating a + configuration with the defaults will yield a similar configuration to that of the SeamlessM4T + ["facebook/hf-seamless-m4t-medium"](https://huggingface.co/"facebook/hf-seamless-m4t-medium") architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + + Args: + vocab_size (`int`, *optional*, defaults to 256102): + Vocabulary size of the SeamlessM4T model. Defines the number of different tokens that can be represented by + the `inputs_ids` passed when calling [`~SeamlessM4TModel`], [`~SeamlessM4TForTextToSpeech`] or + [`~SeamlessM4TForTextToText`]. + t2u_vocab_size (`int`, *optional*, defaults to 10082): + Unit vocabulary size of the SeamlessM4T model. Defines the number of different unit tokens that can be + represented by the `inputs_ids` passed when calling the Text-To-Units sub-model of [`~SeamlessM4TModel`], + [`~SeamlessM4TForSpeechToSpeech`] or [`~SeamlessM4TForTextToSpeech`]. + + > Parameters shared across sub-models + + hidden_size (`int`, *optional*, defaults to 1024): + Dimensionality of the "intermediate" layers in the architecture. + initializer_range (`float`, *optional*, defaults to 0.02): + The standard deviation of the truncated_normal_initializer for initializing all weight matrices. + layer_norm_eps (`float`, *optional*, defaults to 1e-05): + The epsilon used by the layer normalization layers. + use_cache (`bool`, *optional*, defaults to `True`): + Whether or not the model should return the last key/values attentions (not used by all models). + max_position_embeddings (`int`, *optional*, defaults to 1024): + The maximum sequence length that this model text encoder and decoder might ever be used with. Typically set + this to something large just in case (e.g., 512 or 1024 or 2048). + is_encoder_decoder (`bool`, *optional*, defaults to `True`): + Whether the model is used as an encoder/decoder or not. + encoder_layerdrop (`float`, *optional*, defaults to 0.05): + The LayerDrop probability for the encoders. See the [LayerDrop paper](see https://huggingface.co/papers/1909.11556) + for more details. + decoder_layerdrop (`float`, *optional*, defaults to 0.05): + The LayerDrop probability for the decoders. See the [LayerDrop paper](see https://huggingface.co/papers/1909.11556) + for more details. + activation_function (`str` or `function`, *optional*, defaults to `"relu"`): + The non-linear activation function (function or string) in the decoder and feed-forward layers. If string, + `"gelu"`, `"relu"`, `"selu"`, `"swish"` and `"gelu_new"` are supported. + dropout (`float`, *optional*, defaults to 0.1): + The dropout probability for all fully connected layers in the embeddings, encoder, decoder, and pooler. + attention_dropout (`float`, *optional*, defaults to 0.1): + The dropout probability for all attention layers. + activation_dropout (`float`, *optional*, defaults to 0.0): + The dropout probability for all activation layers in the model. + scale_embedding (`bool`, *optional*, defaults to `True`): + Scale embeddings by diving by sqrt(d_model). + + > Text encoder and text decoder specific parameters + + encoder_layers (`int`, *optional*, defaults to 24): + Number of hidden layers in the Transformer text encoder. + encoder_ffn_dim (`int`, *optional*, defaults to 8192): + Dimension of the "intermediate" (i.e., feed-forward) layer in the Transformer text encoder. + encoder_attention_heads (`int`, *optional*, defaults to 16): + Number of attention heads for each attention layer in the Transformer text encoder. + decoder_layers (`int`, *optional*, defaults to 24): + Number of hidden layers in the Transformer text decoder. + decoder_ffn_dim (`int`, *optional*, defaults to 8192): + Dimension of the "intermediate" (i.e., feed-forward) layer in the Transformer text decoder. + decoder_attention_heads (`int`, *optional*, defaults to 16): + Number of attention heads for each attention layer in the Transformer text decoder. + decoder_start_token_id (`int`, *optional*, defaults to 3): + If an encoder-decoder model starts decoding with a different token than _bos_, the id of that token. Only + applied in the text decoder. + max_new_tokens (`int`, *optional*, defaults to 256): + The maximum numbers of text tokens to generate, ignoring the number of tokens in the prompt. + pad_token_id (`int`, *optional*, defaults to 0): + The id of the _padding_ text token. Only applied to the text-decoder model. + bos_token_id (`int`, *optional*, defaults to 2): + The id of the _beginning-of-stream_ text token. Only applied to the text-decoder model. + eos_token_id (`int`, *optional*, defaults to 3): + The id of the _end-of-stream_ text token. Only applied to the text-decoder model. + + > Speech encoder specific parameters + + speech_encoder_layers (`int`, *optional*, defaults to 24): + Number of hidden layers in the Transformer speech encoder. + speech_encoder_attention_heads (`int`, *optional*, defaults to 16): + Number of attention heads for each attention layer in the Transformer speech encoder. + speech_encoder_intermediate_size (`int`, *optional*, defaults to 4096): + Dimension of the "intermediate" (i.e., feed-forward) layer in the Transformer speech encoder. + speech_encoder_hidden_act (`str` or `function`, *optional*, defaults to `"swish"`): + The non-linear activation function (function or string) in the speech encoder. If string, `"gelu"`, + `"relu"`, `"selu"`, `"swish"` and `"gelu_new"` are supported. + speech_encoder_dropout (`float`, *optional*, defaults to 0.0): + The dropout probability for all layers in the speech encoder. + add_adapter (`bool`, *optional*, defaults to `True`): + Add an adapter layer on top of the speech encoder. + speech_encoder_layerdrop (`float`, *optional*, defaults to 0.1): + The LayerDrop probability for the speech encoder. See the [LayerDrop paper](see + https://huggingface.co/papers/1909.11556) for more details. + feature_projection_input_dim (`int`, *optional*, defaults to 160): + Input dimension of the input feature projection of the speech encoder, i.e the dimension after processing + input audios with [`SeamlessM4TFeatureExtractor`]. + num_conv_pos_embeddings (`int`, *optional*, defaults to 128): + Number of convolutional positional embeddings. Defines the kernel size of 1D convolutional positional + embeddings layer of the speech encoder. + num_conv_pos_embedding_groups (`int`, *optional*, defaults to 16): + Number of groups of 1D convolutional positional embeddings layer of the speech encoder. + adaptor_kernel_size (`int`, *optional*, defaults to 8): + Kernel size of the convolutional layers in the adapter network. Only relevant if `add_adapter is True`. + adaptor_stride (`int`, *optional*, defaults to 8): + Stride of the convolutional layers in the adapter network. Only relevant if `add_adapter is True`. + adaptor_dropout (`float`, *optional*, defaults to 0.1): + The dropout probability for all layers in the speech adapter. + num_adapter_layers (`int`, *optional*, defaults to 1): + Number of convolutional layers that should be used in the adapter network. Only relevant if `add_adapter is + True`. + position_embeddings_type (`str`, *optional*, defaults to `"relative"`): + Can be specified to `relative` or `rotary` for relative or rotary position embeddings respectively. If left + `None` no relative position embedding is applied. Only applied to the speech encoder. + rotary_embedding_base (`int`, *optional*, defaults to 10000): + If `"rotary"` position embeddings are used, defines the size of the embedding base. Only applied to the + speech encoder. + max_source_positions (`int`, *optional*, defaults to 4096): + if `"relative"` position embeddings are used, defines the maximum source input positions. Only applied to + the speech encoder. + conv_depthwise_kernel_size (`int`, *optional*, defaults to 31): + Kernel size of convolutional depthwise 1D layer in Conformer blocks. Only applied to the speech encoder. + + > Text-To-Unit (t2u) model specific parameters + + t2u_bos_token_id (`int`, *optional*, defaults to 0): + The id of the _beginning-of-stream_ unit token. Only applied to the text-to-unit seq2seq model. + t2u_pad_token_id (`int`, *optional*, defaults to 1): + The id of the _padding_ unit token. Only applied to the text-to-unit seq2seq model. + t2u_eos_token_id (`int`, *optional*, defaults to 2): + The id of the _end-of-stream_ unit token. Only applied to the text-to-unit seq2seq model. + t2u_decoder_start_token_id (`int`, *optional*, defaults to 2): + If an encoder-decoder model starts decoding with a different token than _bos_, the id of that token. Only + applied to the text-to-unit seq2seq model. + t2u_max_new_tokens (`int`, *optional*, defaults to 1024): + The maximum numbers of unit tokens to generate, ignoring the number of tokens in the prompt. Only applied + to the text-to-unit seq2seq model. + t2u_encoder_layers (`int`, *optional*, defaults to 6): + Number of hidden layers in the Transformer text-to-unit encoder. + t2u_encoder_ffn_dim (`int`, *optional*, defaults to 8192): + Dimension of the "intermediate" (i.e., feed-forward) layer in the Transformer text-to-unit encoder. + t2u_encoder_attention_heads (`int`, *optional*, defaults to 16): + Number of attention heads for each attention layer in the Transformer text-to-unit encoder. + t2u_decoder_layers (`int`, *optional*, defaults to 6): + Number of hidden layers in the Transformer text-to-unit decoder. + t2u_decoder_ffn_dim (`int`, *optional*, defaults to 8192): + Dimension of the "intermediate" (i.e., feed-forward) layer in the Transformer text-to-unit decoder. + t2u_decoder_attention_heads (`int`, *optional*, defaults to 16): + Number of attention heads for each attention layer in the Transformer text-to-unit decoder. + t2u_max_position_embeddings (`int`, *optional*, defaults to 2048): + The maximum sequence length that this model text-to-unit component might ever be used with. Typically set + this to something large just in case (e.g., 512 or 1024 or 2048). + + > Hifi-Gan Vocoder specific parameters + + sampling_rate (`int`, *optional*, defaults to 16000): + The sampling rate at which the output audio will be generated, expressed in hertz (Hz). + upsample_initial_channel (`int`, *optional*, defaults to 512): + The number of input channels into the hifi-gan upsampling network. Applies to the vocoder only. + upsample_rates (`tuple[int]` or `list[int]`, *optional*, defaults to `[5, 4, 4, 2, 2]`): + A tuple of integers defining the stride of each 1D convolutional layer in the vocoder upsampling network. + The length of *upsample_rates* defines the number of convolutional layers and has to match the length of + *upsample_kernel_sizes*. Applies to the vocoder only. + upsample_kernel_sizes (`tuple[int]` or `list[int]`, *optional*, defaults to `[11, 8, 8, 4, 4]`): + A tuple of integers defining the kernel size of each 1D convolutional layer in the vocoder upsampling + network. The length of *upsample_kernel_sizes* defines the number of convolutional layers and has to match + the length of *upsample_rates*. Applies to the vocoder only. + resblock_kernel_sizes (`tuple[int]` or `list[int]`, *optional*, defaults to `[3, 7, 11]`): + A tuple of integers defining the kernel sizes of the vocoder 1D convolutional layers in the multi-receptive + field fusion (MRF) module. Applies to the vocoder only. + resblock_dilation_sizes (`tuple[tuple[int]]` or `list[list[int]]`, *optional*, defaults to `[[1, 3, 5], [1, 3, 5], [1, 3, 5]]`): + A nested tuple of integers defining the dilation rates of the vocoder dilated 1D convolutional layers in + the multi-receptive field fusion (MRF) module. Applies to the vocoder only. + leaky_relu_slope (`float`, *optional*, defaults to 0.1): + The angle of the negative slope used by the leaky ReLU activation in the vocoder. Applies to the vocoder + only. + unit_hifi_gan_vocab_size (`int`, *optional*, defaults to 10000): + Vocabulary size of the SeamlessM4T vocoder. Defines the number of different unit tokens that can be + represented by the `inputs_ids` passed when calling the vocoder of [`~SeamlessM4TModel`], + [`~SeamlessM4TForSpeechToSpeech`] or [`~SeamlessM4TForTextToSpeech`]. + unit_embed_dim (`int`, *optional*, defaults to 1280): + The projection dimension of the input ids given to the hifi-gan vocoder. Applies to the vocoder only. + lang_embed_dim (`int`, *optional*, defaults to 256): + The projection dimension of the target language given to the hifi-gan vocoder. Applies to the vocoder only. + spkr_embed_dim (`int`, *optional*, defaults to 256): + The projection dimension of the speaker id given to the hifi-gan vocoder. Applies to the vocoder only. + vocoder_num_langs (`int`, *optional*, defaults to 36): + Number of langs supported by the vocoder. Might be different from `t2u_num_langs`. + vocoder_num_spkrs (`int`, *optional*, defaults to 200): + Number of speakers supported by the vocoder. + variance_predictor_kernel_size (`int`, *optional*, defaults to 3): + Kernel size of the duration predictor. Applies to the vocoder only. + var_pred_dropout (`float`, *optional*, defaults to 0.5): + The dropout probability of the duration predictor. Applies to the vocoder only. + vocoder_offset (`int`, *optional*, defaults to 4): + Offset the unit token ids by this number to account for symbol tokens. Applies to the vocoder only. + + ```python + >>> from transformers import SeamlessM4TModel, SeamlessM4TConfig + + >>> # Initializing a SeamlessM4T "facebook/hf-seamless-m4t-medium" style configuration + >>> configuration = SeamlessM4TConfig() + + >>> # Initializing a model from the "facebook/hf-seamless-m4t-medium" style configuration + >>> model = SeamlessM4TModel(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "seamless_m4t" + + def __init__( + self, + vocab_size=256102, + t2u_vocab_size=10082, + # shared config + hidden_size=1024, + initializer_range=0.02, + layer_norm_eps=1e-5, + use_cache=True, + max_position_embeddings=1024, + is_encoder_decoder=True, + encoder_layerdrop=0.05, + decoder_layerdrop=0.05, + activation_function="relu", + dropout=0.1, + attention_dropout=0.1, + activation_dropout=0.0, + scale_embedding=True, + # text encoder|decoder + encoder_layers=24, + encoder_ffn_dim=8192, + encoder_attention_heads=16, + decoder_layers=24, + decoder_ffn_dim=8192, + decoder_attention_heads=16, + decoder_start_token_id=3, + max_new_tokens=256, + pad_token_id=0, + bos_token_id=2, + eos_token_id=3, + # speech_encoder + speech_encoder_layers=24, + speech_encoder_attention_heads=16, + speech_encoder_intermediate_size=4096, + speech_encoder_hidden_act="swish", + speech_encoder_dropout=0.0, + add_adapter=True, + speech_encoder_layerdrop=0.1, + feature_projection_input_dim=160, + num_conv_pos_embeddings=128, + num_conv_pos_embedding_groups=16, + adaptor_kernel_size=8, + adaptor_stride=8, + adaptor_dropout=0.1, + num_adapter_layers=1, + position_embeddings_type="relative", + rotary_embedding_base=10000, + max_source_positions=4096, + conv_depthwise_kernel_size=31, + # t2u config + t2u_bos_token_id=0, + t2u_pad_token_id=1, + t2u_eos_token_id=2, + t2u_decoder_start_token_id=2, + t2u_max_new_tokens=1024, + t2u_encoder_layers=6, + t2u_encoder_ffn_dim=8192, + t2u_encoder_attention_heads=16, + t2u_decoder_layers=6, + t2u_decoder_ffn_dim=8192, + t2u_decoder_attention_heads=16, + t2u_max_position_embeddings=2048, + # hifi-gan vocoder config + sampling_rate=16000, + upsample_initial_channel=512, + upsample_rates=[5, 4, 4, 2, 2], + upsample_kernel_sizes=[11, 8, 8, 4, 4], + resblock_kernel_sizes=[3, 7, 11], + resblock_dilation_sizes=[[1, 3, 5], [1, 3, 5], [1, 3, 5]], + leaky_relu_slope=0.1, + # specific to Code Hifi-Gan + unit_hifi_gan_vocab_size=10000, + unit_embed_dim=1280, + lang_embed_dim=256, + spkr_embed_dim=256, + vocoder_num_langs=36, + vocoder_num_spkrs=200, + variance_predictor_kernel_size=3, + var_pred_dropout=0.5, + vocoder_offset=4, + tie_word_embeddings=True, + **kwargs, + ): + # overall_config + self.vocab_size = vocab_size + self.t2u_vocab_size = t2u_vocab_size + self.hidden_size = hidden_size + self.initializer_range = initializer_range + self.layer_norm_eps = layer_norm_eps + self.max_position_embeddings = max_position_embeddings + self.use_cache = use_cache + self.max_new_tokens = max_new_tokens + self.encoder_layerdrop = encoder_layerdrop + self.decoder_layerdrop = decoder_layerdrop + self.activation_function = activation_function + self.dropout = dropout + self.attention_dropout = attention_dropout + self.activation_dropout = activation_dropout + self.scale_embedding = scale_embedding + self.tie_word_embeddings = tie_word_embeddings + # for proper config init + self.num_attention_heads = decoder_attention_heads + self.num_hidden_layers = decoder_layers + + # text|unit encoder|decoder + self.encoder_layers = encoder_layers + self.encoder_ffn_dim = encoder_ffn_dim + self.encoder_attention_heads = encoder_attention_heads + self.decoder_layers = decoder_layers + self.decoder_ffn_dim = decoder_ffn_dim + self.decoder_attention_heads = decoder_attention_heads + + # speech_encoder + self.speech_encoder_layers = speech_encoder_layers + self.speech_encoder_hidden_act = speech_encoder_hidden_act + self.speech_encoder_dropout = speech_encoder_dropout + self.speech_encoder_attention_heads = speech_encoder_attention_heads + self.speech_encoder_layerdrop = speech_encoder_layerdrop + self.speech_encoder_intermediate_size = speech_encoder_intermediate_size + self.feature_projection_input_dim = feature_projection_input_dim + self.num_conv_pos_embeddings = num_conv_pos_embeddings + self.num_conv_pos_embedding_groups = num_conv_pos_embedding_groups + self.adaptor_kernel_size = adaptor_kernel_size + self.adaptor_stride = adaptor_stride + self.adaptor_dropout = adaptor_dropout + self.num_adapter_layers = num_adapter_layers + self.position_embeddings_type = position_embeddings_type + self.rotary_embedding_base = rotary_embedding_base + self.max_source_positions = max_source_positions + self.conv_depthwise_kernel_size = conv_depthwise_kernel_size + self.add_adapter = add_adapter + + # t2u config + self.t2u_bos_token_id = t2u_bos_token_id + self.t2u_pad_token_id = t2u_pad_token_id + self.t2u_eos_token_id = t2u_eos_token_id + self.t2u_decoder_start_token_id = t2u_decoder_start_token_id + self.t2u_max_new_tokens = t2u_max_new_tokens + self.t2u_encoder_layers = t2u_encoder_layers + self.t2u_encoder_ffn_dim = t2u_encoder_ffn_dim + self.t2u_encoder_attention_heads = t2u_encoder_attention_heads + self.t2u_decoder_layers = t2u_decoder_layers + self.t2u_decoder_ffn_dim = t2u_decoder_ffn_dim + self.t2u_decoder_attention_heads = t2u_decoder_attention_heads + self.t2u_max_position_embeddings = t2u_max_position_embeddings + + # hifi-gan vocoder config + # original parameters specific to Hifi-Gan + self.sampling_rate = sampling_rate + self.upsample_initial_channel = upsample_initial_channel + self.upsample_rates = upsample_rates + self.upsample_kernel_sizes = upsample_kernel_sizes + self.resblock_kernel_sizes = resblock_kernel_sizes + self.resblock_dilation_sizes = resblock_dilation_sizes + self.leaky_relu_slope = leaky_relu_slope + + # specific to Code Hifi-Gan + self.unit_hifi_gan_vocab_size = unit_hifi_gan_vocab_size + self.unit_embed_dim = unit_embed_dim + self.lang_embed_dim = lang_embed_dim + self.spkr_embed_dim = spkr_embed_dim + self.vocoder_num_langs = vocoder_num_langs + self.vocoder_num_spkrs = vocoder_num_spkrs + self.variance_predictor_kernel_size = variance_predictor_kernel_size + self.var_pred_dropout = var_pred_dropout + self.vocoder_offset = vocoder_offset + self.pad_token_id = pad_token_id + self.bos_token_id = bos_token_id + self.eos_token_id = eos_token_id + self.max_position_embeddings = max_position_embeddings + self.decoder_start_token_id = decoder_start_token_id + + super().__init__(is_encoder_decoder=is_encoder_decoder, **kwargs) + + +__all__ = ["SeamlessM4TConfig"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/seamless_m4t/feature_extraction_seamless_m4t.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/seamless_m4t/feature_extraction_seamless_m4t.py new file mode 100644 index 0000000000000000000000000000000000000000..1b18dcc33404223471e7fbd16f4e1210faed512e --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/seamless_m4t/feature_extraction_seamless_m4t.py @@ -0,0 +1,305 @@ +# Copyright 2023 The HuggingFace Inc. team. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +""" +Feature extractor class for SeamlessM4T +""" + +import numpy as np + +from ...utils import is_torch_available + + +if is_torch_available(): + import torch + +from ...audio_utils import mel_filter_bank, spectrogram, window_function +from ...feature_extraction_sequence_utils import SequenceFeatureExtractor +from ...feature_extraction_utils import BatchFeature +from ...utils import PaddingStrategy, TensorType, logging + + +logger = logging.get_logger(__name__) + + +class SeamlessM4TFeatureExtractor(SequenceFeatureExtractor): + r""" + Constructs a SeamlessM4T feature extractor. + + This feature extractor inherits from [`SequenceFeatureExtractor`] which contains most of the main methods. Users + should refer to this superclass for more information regarding those methods. + + This class extracts mel-filter bank features from raw speech. + + Args: + feature_size (`int`, *optional*, defaults to 80): + The feature dimension of the extracted features. + sampling_rate (`int`, *optional*, defaults to 16000): + The sampling rate at which the audio files should be digitalized expressed in hertz (Hz). + num_mel_bins (`int`, *optional*, defaults to 80): + Number of Mel-frequency bins. + padding_value (`float`, *optional*, defaults to 0.0): + The value that is used to fill the padding vectors. + stride (`int`, *optional*, defaults to 2): + Stride used to reshape audios from shape (batch_size,num_frames,num_mel_bins) to + (batch_size,num_frames//stride,num_mel_bins*stride). + """ + + model_input_names = ["input_features", "attention_mask"] + + def __init__( + self, + feature_size=80, + sampling_rate=16000, + num_mel_bins=80, + padding_value=0.0, + stride=2, + **kwargs, + ): + self.num_mel_bins = num_mel_bins + self.return_attention_mask = True + self.stride = stride + + mel_filters = mel_filter_bank( + num_frequency_bins=257, + num_mel_filters=self.num_mel_bins, + min_frequency=20, + max_frequency=sampling_rate // 2, + sampling_rate=sampling_rate, + norm=None, + mel_scale="kaldi", + triangularize_in_mel_space=True, + ) + + self.mel_filters = mel_filters + self.window = window_function(400, "povey", periodic=False) + + super().__init__(feature_size=feature_size, sampling_rate=sampling_rate, padding_value=padding_value, **kwargs) + + @staticmethod + # Copied from transformers.models.wav2vec2.feature_extraction_wav2vec2.Wav2Vec2FeatureExtractor.zero_mean_unit_var_norm + def zero_mean_unit_var_norm( + input_values: list[np.ndarray], attention_mask: list[np.ndarray], padding_value: float = 0.0 + ) -> list[np.ndarray]: + """ + Every array in the list is normalized to have zero mean and unit variance + """ + if attention_mask is not None: + attention_mask = np.array(attention_mask, np.int32) + normed_input_values = [] + + for vector, length in zip(input_values, attention_mask.sum(-1)): + normed_slice = (vector - vector[:length].mean()) / np.sqrt(vector[:length].var() + 1e-7) + if length < normed_slice.shape[0]: + normed_slice[length:] = padding_value + + normed_input_values.append(normed_slice) + else: + normed_input_values = [(x - x.mean()) / np.sqrt(x.var() + 1e-7) for x in input_values] + + return normed_input_values + + def _extract_fbank_features( + self, + waveform: np.ndarray, + ) -> np.ndarray: + """ + Get mel-filter bank features using TorchAudio. Note that TorchAudio requires 16-bit signed integers as inputs + and hence the waveform should not be normalized before feature extraction. + """ + # by default, it extracts the left channel if stereo + if len(waveform.shape) == 2: + waveform = waveform[0] + + waveform = np.squeeze(waveform) * (2**15) # Kaldi compliance: 16-bit signed integers + features = spectrogram( + waveform, + self.window, + frame_length=400, + hop_length=160, + fft_length=512, + power=2.0, + center=False, + preemphasis=0.97, + mel_filters=self.mel_filters, + log_mel="log", + mel_floor=1.192092955078125e-07, + remove_dc_offset=True, + ).T + return features + + def __call__( + self, + raw_speech: np.ndarray | list[float] | list[np.ndarray] | list[list[float]], + padding: bool | str | PaddingStrategy = True, + pad_to_multiple_of: int | None = 2, + max_length: int | None = None, + truncation: bool = False, + return_tensors: str | TensorType | None = None, + sampling_rate: int | None = None, + return_attention_mask: bool | None = None, + do_normalize_per_mel_bins: bool | None = True, + **kwargs, + ) -> BatchFeature: + """ + Main method to featurize and prepare for the model one or several sequence(s). + + Args: + raw_speech (`np.ndarray`, `torch.Tensor`, `list[float]`, `list[np.ndarray]`, `list[torch.Tensor]`, + `list[list[float]]`, `list[list[list[float]]]`): + The sequence or batch of sequences to be padded. Each sequence can be a numpy array, + a torch tensor, a list of float values, a list of numpy arrays, a list of torch tensors, + a list of list of float values or a list of a list of list of float values. + If `raw_speech` is a one-dimensional `np.ndarray`, `torch.Tensor` or a `list[float]`, `raw_speech` is + considered a single-channel, single-sample sound. In all other cases, the first dimension of + `raw_speech`, whether from an `np.ndarray`, a `torch.Tensor` or a `list[...]`, + corresponds to the number of samples in the batch, and the number of channels + (i.e. mono or stereo character) is derived from the other dimensions + (1D -> single-channel waveform batches; 2D-> stereo-channel waveform batches). + padding (`bool`, `str` or [`~utils.PaddingStrategy`], *optional*, defaults to `True`): + Select a strategy to pad the returned sequences (according to the model's padding side and padding + index) among: + + - `True` or `'longest'`: Pad to the longest sequence in the batch (or no padding if only a single + sequence if provided). + - `'max_length'`: Pad to a maximum length specified with the argument `max_length` or to the maximum + acceptable input length for the model if that argument is not provided. + - `False` or `'do_not_pad'` (default): No padding (i.e., can output a batch with sequences of different + lengths). + pad_to_multiple_of (`int`, *optional*, defaults to 2): + If set will pad the sequence to a multiple of the provided value. + + This is especially useful to enable the use of Tensor Cores on NVIDIA hardware with compute capability + `>= 7.5` (Volta), or on TPUs which benefit from having sequence lengths be a multiple of 128. + max_length (`int`, *optional*): + Maximum length of the returned list and optionally padding length (see above). + truncation (`bool`): + Activates truncation to cut input sequences longer than *max_length* to *max_length*. + return_attention_mask (`bool`, *optional*): + Whether to return the attention mask. If left to the default, will return the attention mask according + to the specific feature_extractor's default. + + [What are attention masks?](../glossary#attention-mask) + + + + For SeamlessM4T models, `attention_mask` should always be passed for batched inference, to avoid subtle + bugs. + + + + return_tensors (`str` or [`~utils.TensorType`], *optional*): + If set, will return tensors instead of list of python integers. Acceptable values are: + + - `'pt'`: Return PyTorch `torch.Tensor` objects. + - `'np'`: Return Numpy `np.ndarray` objects. + sampling_rate (`int`, *optional*): + The sampling rate at which the `raw_speech` input was sampled. It is strongly recommended to pass + `sampling_rate` at the forward call to prevent silent errors. + do_normalize_per_mel_bins (`bool`, *optional*, defaults to `True`): + Whether or not to zero-mean unit-variance normalize the input per mel-channel. + kwargs (*optional*): + Remaining dictionary of keyword arguments that will be passed to the tokenizer or the feature + extractor. + """ + if sampling_rate is not None: + if sampling_rate != self.sampling_rate: + raise ValueError( + f"The model corresponding to this feature extractor: {self} was trained using a sampling rate of" + f" {self.sampling_rate}. Please make sure that the provided `raw_speech` input was sampled with" + f" {self.sampling_rate} and not {sampling_rate}." + ) + else: + logger.warning( + f"It is strongly recommended to pass the `sampling_rate` argument to `{self.__class__.__name__}()`. " + "Failing to do so can result in silent errors that might be hard to debug." + ) + + return_attention_mask = ( + return_attention_mask if return_attention_mask is not None else self.return_attention_mask + ) + + is_batched_numpy = isinstance(raw_speech, np.ndarray) and len(raw_speech.shape) > 1 + if is_batched_numpy and len(raw_speech.shape) > 3: + raise ValueError(f"Only mono-channel or stereo-channel audio is supported for input to {self}") + + acceptable_types = ( + (torch.Tensor, np.ndarray, tuple, list) if is_torch_available() else (np.ndarray, tuple, list) + ) + is_batched = is_batched_numpy or ( + isinstance(raw_speech, (list, tuple)) and (isinstance(raw_speech[0], acceptable_types)) + ) + + if is_batched: + raw_speech = [np.asarray(speech, dtype=np.float32) for speech in raw_speech] + elif not is_batched and not isinstance(raw_speech, np.ndarray): + raw_speech = np.asarray(raw_speech, dtype=np.float32) + elif isinstance(raw_speech, np.ndarray) and raw_speech.dtype is np.dtype(np.float64): + raw_speech = raw_speech.astype(np.float32) + + # always return batch + if not is_batched: + raw_speech = [raw_speech] + + # extract fbank features + features = [self._extract_fbank_features(waveform) for waveform in raw_speech] + + if do_normalize_per_mel_bins: + # torch defaults to ddof=1, and numpy defaults to ddof=0 + features = [ + (x - np.expand_dims(x.mean(0), 0)) / np.sqrt(np.expand_dims(x.var(0, ddof=1), 0) + 1e-7) + for x in features + ] + + # convert into correct format for padding + encoded_inputs = BatchFeature({"input_features": features}) + + padded_inputs = self.pad( + encoded_inputs, + padding=padding, + max_length=max_length, + truncation=truncation, + pad_to_multiple_of=pad_to_multiple_of, + return_attention_mask=True, + return_tensors="np", + ) + + # SeamlessM4T needs to process extracted features + input_features = padded_inputs.get("input_features") + attention_mask = padded_inputs.pop("attention_mask") + + batch_size, num_frames, num_channels = input_features.shape + + remainder = num_frames % self.stride + if remainder != 0: + input_features = input_features[:, : num_frames - remainder, :] + attention_mask = attention_mask[:, : num_frames - remainder] + + input_features = np.reshape( + input_features, (batch_size, num_frames // self.stride, num_channels * self.stride) + ) + + indices = np.arange(0, num_frames - remainder) + attention_mask = attention_mask[:, indices % self.stride == 1] + + padded_inputs["input_features"] = input_features + if return_attention_mask: + padded_inputs["attention_mask"] = attention_mask + + if return_tensors is not None: + padded_inputs = padded_inputs.convert_to_tensors(return_tensors) + + return padded_inputs + + +__all__ = ["SeamlessM4TFeatureExtractor"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/seamless_m4t/modeling_seamless_m4t.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/seamless_m4t/modeling_seamless_m4t.py new file mode 100644 index 0000000000000000000000000000000000000000..e37ee7e645482011d6ca8d1954bb38ec55624434 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/seamless_m4t/modeling_seamless_m4t.py @@ -0,0 +1,4054 @@ +# Copyright 2023 The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""PyTorch SeamlessM4T model.""" + +import copy +import math +from dataclasses import dataclass + +import torch +from torch import Tensor, nn +from torch.nn import CrossEntropyLoss + +from ... import initialization as init +from ...activations import ACT2FN +from ...cache_utils import Cache, DynamicCache, EncoderDecoderCache +from ...generation import GenerationMixin +from ...integrations.deepspeed import is_deepspeed_zero3_enabled +from ...integrations.fsdp import is_fsdp_managed_module +from ...masking_utils import create_bidirectional_mask, create_causal_mask +from ...modeling_layers import GradientCheckpointingLayer +from ...modeling_outputs import ( + BaseModelOutput, + BaseModelOutputWithPastAndCrossAttentions, + Seq2SeqLMOutput, + Seq2SeqModelOutput, + Wav2Vec2BaseModelOutput, +) +from ...modeling_utils import PreTrainedModel +from ...utils import ModelOutput, auto_docstring, logging +from ...utils.deprecation import deprecate_kwarg +from .configuration_seamless_m4t import SeamlessM4TConfig + + +logger = logging.get_logger(__name__) + +SEAMLESS_M4T_COMMON_CUSTOM_ARGS = r""" + input_features (`torch.FloatTensor` of shape `(batch_size, sequence_length, num_banks)`): + Input audio features. This should be returned by the [`SeamlessM4TFeatureExtractor`] class or the + [`SeamlessM4TProcessor`] class. See [`SeamlessM4TFeatureExtractor.__call__`] for details. + decoder_input_ids (`torch.LongTensor` of shape `(batch_size, target_sequence_length)`, *optional*): + Indices of decoder input sequence tokens in the vocabulary. + + Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and + [`PreTrainedTokenizer.__call__`] for details. + + [What are decoder input IDs?](../glossary#decoder-input-ids) + + Bart uses the `eos_token_id` as the starting token for `decoder_input_ids` generation. If `past_key_values` + is used, optionally only the last `decoder_input_ids` have to be input (see `past_key_values`). + + For translation and summarization training, `decoder_input_ids` should be provided. If no + `decoder_input_ids` is provided, the model will create this tensor by shifting the `input_ids` to the right + for denoising pre-training following the paper. + decoder_attention_mask (`torch.LongTensor` of shape `(batch_size, target_sequence_length)`, *optional*): + Default behavior: generate a tensor that ignores pad tokens in `decoder_input_ids`. Causal mask will also + be used by default. + + If you want to change padding behavior, you should read [`modeling_bart._prepare_decoder_attention_mask`] + and modify to your needs. See diagram 1 in [the paper](https://huggingface.co/papers/1910.13461) for more + information on the default strategy. + inputs_embeds (`torch.FloatTensor` of shape`(batch_size, sequence_length, hidden_size)`, *optional*): + Optionally, instead of passing `input_ids` you can choose to directly pass an embedded representation. This + is useful if you want more control over how to convert `input_ids` indices into associated vectors than the + model's internal embedding lookup matrix. +""" + + +@dataclass +@auto_docstring( + custom_intro=""" + Class defining the generated outputs from [`SeamlessM4TModel`], [`SeamlessM4TForTextToText`], + [`SeamlessM4TForTextToSpeech`], [`SeamlessM4TForSpeechToSpeech`] and [`SeamlessM4TForTextToSpeech`]. + """ +) +class SeamlessM4TGenerationOutput(ModelOutput): + r""" + waveform (`torch.FloatTensor` of shape `(batch_size, sequence_length)`): + The final audio waveform predicted by the model. + waveform_lengths (`torch.IntTensor` of shape `(batch_size,)`, *optional*): + The length in samples of each element in the `waveform` batch. + sequences (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + The generated translated sequences. This is the output of the text-to-text or the speech-to-text models. + The second dimension (sequence_length) is either equal to `max_length` or shorter if all batches finished + early due to the `eos_token_id`. + unit_sequences (`torch.LongTensor` of shape `(batch_size, unit_sequence_length)`, *optional*): + The generated translated unit sequences. This is the output of the text-to-units model. The second + dimension (unit_sequence_length) is either equal to `t2u_max_length` or shorter if all batches finished + early due to the `t2u_eos_token_id`. + """ + + waveform: torch.FloatTensor | None = None + waveform_lengths: torch.IntTensor | None = None + sequences: tuple[torch.FloatTensor] | None = None + unit_sequences: tuple[torch.FloatTensor] | None = None + + +############ UTILS ################ + + +# Copied from transformers.models.bart.modeling_bart.shift_tokens_right +def shift_tokens_right(input_ids: torch.Tensor, pad_token_id: int, decoder_start_token_id: int): + """ + Shift input ids one token to the right. + """ + shifted_input_ids = input_ids.new_zeros(input_ids.shape) + shifted_input_ids[:, 1:] = input_ids[:, :-1].clone() + shifted_input_ids[:, 0] = decoder_start_token_id + + if pad_token_id is None: + raise ValueError("self.model.config.pad_token_id has to be defined.") + # replace possible -100 values in labels by `pad_token_id` + shifted_input_ids.masked_fill_(shifted_input_ids == -100, pad_token_id) + + return shifted_input_ids + + +def _compute_new_attention_mask(hidden_states: torch.Tensor, seq_lens: torch.Tensor): + """ + Computes an attention mask of the form `(batch, seq_len)` with an attention for each element in the batch that + stops at the corresponding element in `seq_lens`. + + Args: + hidden_states (`torch.FloatTensor` of shape `(batch, seq_len, *)`): + The sequences to mask, where `*` is any number of sequence-specific dimensions including none. + seq_lens (`torch.Tensor` of shape `(batch)`: + Each element represents the length of the sequence at the same index in `hidden_states` + + Returns: + `torch.FloatTensor`: The float attention mask of shape `(batch, seq_len)` + """ + batch_size, mask_seq_len = hidden_states.shape[:2] + + indices = torch.arange(mask_seq_len, device=seq_lens.device).expand(batch_size, -1) + + bool_mask = indices >= seq_lens.unsqueeze(1).expand(-1, mask_seq_len) + + mask = hidden_states.new_ones((batch_size, mask_seq_len)) + + mask = mask.masked_fill(bool_mask, 0) + + return mask + + +def format_speech_generation_kwargs(kwargs): + """ + Format kwargs for SeamlessM4T models that generate speech, attribute kwargs to either the text generation or the + speech generation models. + + Args: + kwargs (`dict`)`: + Keyword arguments are of two types: + + - Without a prefix, they will be entered as `**kwargs` for the `generate` method of each sub-model, + except for `decoder_input_ids` which will only be passed through the text components. + - With a *text_* or *speech_* prefix, they will be input for the `generate` method of the + text model and speech model respectively. It has the priority over the keywords without a prefix. + + This means you can, for example, specify a generation strategy for one generation but not for the + other. + """ + # attribute kwargs to models + kwargs_text = {} + kwargs_speech = {} + for key, value in kwargs.items(): + if key.startswith("text_"): + key = key[len("text_") :] + kwargs_text[key] = value + elif key.startswith("speech_"): + key = key[len("speech_") :] + kwargs_speech[key] = value + elif key == "generation_config": + kwargs_text[key] = value + else: + # If the key is already in a specific config, then it's been set with a + # submodules specific value and we don't override + if key not in kwargs_text: + kwargs_text[key] = value + if key not in kwargs_speech: + kwargs_speech[key] = value + return kwargs_text, kwargs_speech + + +############ SPEECH ENCODER related code ################ + + +# Copied from transformers.models.wav2vec2.modeling_wav2vec2.Wav2Vec2PositionalConvEmbedding with Wav2Vec2->SeamlessM4TConformer, feat_extract_activation->speech_encoder_hidden_act +class SeamlessM4TConformerPositionalConvEmbedding(nn.Module): + def __init__(self, config): + super().__init__() + self.conv = nn.Conv1d( + config.hidden_size, + config.hidden_size, + kernel_size=config.num_conv_pos_embeddings, + padding=config.num_conv_pos_embeddings // 2, + groups=config.num_conv_pos_embedding_groups, + ) + + weight_norm = nn.utils.weight_norm + if hasattr(nn.utils.parametrizations, "weight_norm"): + weight_norm = nn.utils.parametrizations.weight_norm + + if is_deepspeed_zero3_enabled(): + import deepspeed + + with deepspeed.zero.GatheredParameters(self.conv.weight, modifier_rank=0): + self.conv = weight_norm(self.conv, name="weight", dim=2) + if hasattr(self.conv, "parametrizations"): + weight_g = self.conv.parametrizations.weight.original0 + weight_v = self.conv.parametrizations.weight.original1 + else: + weight_g = self.conv.weight_g + weight_v = self.conv.weight_v + deepspeed.zero.register_external_parameter(self, weight_v) + deepspeed.zero.register_external_parameter(self, weight_g) + else: + self.conv = weight_norm(self.conv, name="weight", dim=2) + + self.padding = SeamlessM4TConformerSamePadLayer(config.num_conv_pos_embeddings) + self.activation = ACT2FN[config.speech_encoder_hidden_act] + + def forward(self, hidden_states): + hidden_states = hidden_states.transpose(1, 2) + + hidden_states = self.conv(hidden_states) + hidden_states = self.padding(hidden_states) + hidden_states = self.activation(hidden_states) + + hidden_states = hidden_states.transpose(1, 2) + return hidden_states + + +# Copied from transformers.models.wav2vec2_conformer.modeling_wav2vec2_conformer.Wav2Vec2ConformerRotaryPositionalEmbedding with Wav2Vec2->SeamlessM4T, num_attention_heads->speech_encoder_attention_heads +class SeamlessM4TConformerRotaryPositionalEmbedding(nn.Module): + """Rotary positional embedding + Reference : https://blog.eleuther.ai/rotary-embeddings/ Paper: https://huggingface.co/papers/2104.09864 + """ + + def __init__(self, config): + super().__init__() + dim = config.hidden_size // config.speech_encoder_attention_heads + base = config.rotary_embedding_base + + inv_freq = 1.0 / (base ** (torch.arange(0, dim, 2, dtype=torch.int64).float() / dim)) + self.register_buffer("inv_freq", inv_freq) + self.cached_sequence_length = None + self.cached_rotary_positional_embedding = None + + def forward(self, hidden_states): + sequence_length = hidden_states.shape[1] + + if sequence_length == self.cached_sequence_length and self.cached_rotary_positional_embedding is not None: + return self.cached_rotary_positional_embedding + + self.cached_sequence_length = sequence_length + # Embeddings are computed in the dtype of the inv_freq constant + time_stamps = torch.arange(sequence_length).type_as(self.inv_freq) + freqs = torch.einsum("i,j->ij", time_stamps, self.inv_freq) + embeddings = torch.cat((freqs, freqs), dim=-1) + + cos_embeddings = embeddings.cos()[:, None, None, :] + sin_embeddings = embeddings.sin()[:, None, None, :] + # Computed embeddings are cast to the dtype of the hidden state inputs + self.cached_rotary_positional_embedding = torch.stack([cos_embeddings, sin_embeddings]).type_as(hidden_states) + return self.cached_rotary_positional_embedding + + +# Copied from transformers.models.wav2vec2_conformer.modeling_wav2vec2_conformer.Wav2Vec2ConformerRelPositionalEmbedding with Wav2Vec2->SeamlessM4T +class SeamlessM4TConformerRelPositionalEmbedding(nn.Module): + """Relative positional encoding module.""" + + def __init__(self, config): + super().__init__() + self.max_len = config.max_source_positions + self.d_model = config.hidden_size + self.register_buffer("pe", self.extend_pe(torch.tensor(0.0).expand(1, self.max_len)), persistent=False) + + def extend_pe(self, x, pe=None): + # Reset the positional encodings + if pe is not None: + # self.pe contains both positive and negative parts + # the length of self.pe is 2 * input_len - 1 + if pe.size(1) >= x.size(1) * 2 - 1: + if pe.dtype != x.dtype or pe.device != x.device: + pe = pe.to(dtype=x.dtype, device=x.device) + return pe + # Suppose `i` is the position of query vector and `j` is the + # position of key vector. We use positive relative positions when keys + # are to the left (i>j) and negative relative positions otherwise (iSeamlessM4T +class SeamlessM4TConformerSamePadLayer(nn.Module): + def __init__(self, num_conv_pos_embeddings): + super().__init__() + self.num_pad_remove = 1 if num_conv_pos_embeddings % 2 == 0 else 0 + + def forward(self, hidden_states): + if self.num_pad_remove > 0: + hidden_states = hidden_states[:, :, : -self.num_pad_remove] + return hidden_states + + +class SeamlessM4TConformerFeatureProjection(nn.Module): + def __init__(self, config): + super().__init__() + self.layer_norm = nn.LayerNorm(config.feature_projection_input_dim, eps=config.layer_norm_eps) + self.projection = nn.Linear(config.feature_projection_input_dim, config.hidden_size) + self.dropout = nn.Dropout(config.speech_encoder_dropout) + + def forward(self, hidden_states): + # non-projected hidden states are needed for quantization + norm_hidden_states = self.layer_norm(hidden_states) + hidden_states = self.projection(norm_hidden_states) + hidden_states = self.dropout(hidden_states) + return hidden_states + + +class SeamlessM4TConformerFeedForward(nn.Module): + def __init__(self, config, act_fn=None, dropout=None): + super().__init__() + dropout = dropout if dropout is not None else config.speech_encoder_dropout + act_fn = act_fn if act_fn is not None else config.speech_encoder_hidden_act + + self.intermediate_dropout = nn.Dropout(dropout) + self.intermediate_dense = nn.Linear(config.hidden_size, config.speech_encoder_intermediate_size) + self.intermediate_act_fn = ACT2FN[act_fn] if isinstance(act_fn, str) else act_fn + + self.output_dense = nn.Linear(config.speech_encoder_intermediate_size, config.hidden_size) + self.output_dropout = nn.Dropout(dropout) + + def forward(self, hidden_states): + hidden_states = self.intermediate_dense(hidden_states) + hidden_states = self.intermediate_act_fn(hidden_states) + hidden_states = self.intermediate_dropout(hidden_states) + + hidden_states = self.output_dense(hidden_states) + hidden_states = self.output_dropout(hidden_states) + return hidden_states + + +class SeamlessM4TConformerConvolutionModule(nn.Module): + """Convolution block used in the conformer block""" + + def __init__(self, config): + super().__init__() + if (config.conv_depthwise_kernel_size - 1) % 2 == 1: + raise ValueError("`config.conv_depthwise_kernel_size` should be a odd number for 'SAME' padding") + self.layer_norm = nn.LayerNorm(config.hidden_size) + self.pointwise_conv1 = nn.Conv1d( + config.hidden_size, + 2 * config.hidden_size, + kernel_size=1, + stride=1, + padding=0, + bias=False, + ) + self.glu = nn.GLU(dim=1) + self.depthwise_conv = nn.Conv1d( + config.hidden_size, + config.hidden_size, + config.conv_depthwise_kernel_size, + stride=1, + padding="same", + groups=config.hidden_size, + bias=False, + ) + self.batch_norm = nn.BatchNorm1d(config.hidden_size) + self.activation = ACT2FN[config.speech_encoder_hidden_act] + self.pointwise_conv2 = nn.Conv1d( + config.hidden_size, + config.hidden_size, + kernel_size=1, + stride=1, + padding=0, + bias=False, + ) + self.dropout = nn.Dropout(config.speech_encoder_dropout) + + def forward(self, hidden_states, attention_mask=None): + hidden_states = self.layer_norm(hidden_states) + + # Ensure that we do not leak padded positions in depthwise convolution. + # Put 0 where necessary + if attention_mask is not None: + hidden_states = hidden_states.masked_fill(~attention_mask.bool().unsqueeze(-1), 0.0) + + # exchange the temporal dimension and the feature dimension + hidden_states = hidden_states.transpose(1, 2) + + # GLU mechanism + # => (batch, 2*channel, dim) + hidden_states = self.pointwise_conv1(hidden_states) + # => (batch, channel, dim) + hidden_states = self.glu(hidden_states) + + # 1D Depthwise Conv + hidden_states = self.depthwise_conv(hidden_states) + hidden_states = self.batch_norm(hidden_states) + hidden_states = self.activation(hidden_states) + + hidden_states = self.pointwise_conv2(hidden_states) + hidden_states = self.dropout(hidden_states) + hidden_states = hidden_states.transpose(1, 2) + return hidden_states + + +class SeamlessM4TConformerSelfAttention(nn.Module): + """Construct a SeamlessM4TConformerSelfAttention object. + Can be enhanced with rotary or relative position embeddings. + """ + + def __init__(self, config, use_position_embeddings=True): + super().__init__() + + self.head_size = config.hidden_size // config.speech_encoder_attention_heads + self.num_heads = config.speech_encoder_attention_heads + self.position_embeddings_type = config.position_embeddings_type if use_position_embeddings else None + + self.linear_q = nn.Linear(config.hidden_size, config.hidden_size) + self.linear_k = nn.Linear(config.hidden_size, config.hidden_size) + self.linear_v = nn.Linear(config.hidden_size, config.hidden_size) + self.linear_out = nn.Linear(config.hidden_size, config.hidden_size) + + self.dropout = nn.Dropout(p=config.speech_encoder_dropout) + + if self.position_embeddings_type == "relative": + # linear transformation for positional encoding + self.linear_pos = nn.Linear(config.hidden_size, config.hidden_size, bias=False) + # these two learnable bias are used in matrix c and matrix d + # as described in https://huggingface.co/papers/1901.02860 Section 3.3 + self.pos_bias_u = nn.Parameter(torch.zeros(self.num_heads, self.head_size)) + self.pos_bias_v = nn.Parameter(torch.zeros(self.num_heads, self.head_size)) + + # Copied from transformers.models.wav2vec2_conformer.modeling_wav2vec2_conformer.Wav2Vec2ConformerSelfAttention.forward + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.Tensor | None = None, + relative_position_embeddings: torch.Tensor | None = None, + output_attentions: bool = False, + ) -> tuple[torch.Tensor, torch.Tensor | None, tuple[torch.Tensor] | None]: + # self-attention mechanism + batch_size, sequence_length, hidden_size = hidden_states.size() + + # make sure query/key states can be != value states + query_key_states = hidden_states + value_states = hidden_states + + if self.position_embeddings_type == "rotary": + if relative_position_embeddings is None: + raise ValueError( + "`relative_position_embeddings` has to be defined when `self.position_embeddings_type == 'rotary'" + ) + query_key_states = self._apply_rotary_embedding(query_key_states, relative_position_embeddings) + + # project query_key_states and value_states + query = self.linear_q(query_key_states).view(batch_size, -1, self.num_heads, self.head_size) + key = self.linear_k(query_key_states).view(batch_size, -1, self.num_heads, self.head_size) + value = self.linear_v(value_states).view(batch_size, -1, self.num_heads, self.head_size) + + # => (batch, head, time1, d_k) + query = query.transpose(1, 2) + key = key.transpose(1, 2) + value = value.transpose(1, 2) + + if self.position_embeddings_type == "relative": + if relative_position_embeddings is None: + raise ValueError( + "`relative_position_embeddings` has to be defined when `self.position_embeddings_type ==" + " 'relative'" + ) + # apply relative_position_embeddings to qk scores + # as proposed in Transformer_XL: https://huggingface.co/papers/1901.02860 + scores = self._apply_relative_embeddings( + query=query, key=key, relative_position_embeddings=relative_position_embeddings + ) + else: + scores = torch.matmul(query, key.transpose(-2, -1)) / math.sqrt(self.head_size) + + # apply attention_mask if necessary + if attention_mask is not None: + scores = scores + attention_mask + + # => (batch, head, time1, time2) + probs = torch.softmax(scores, dim=-1) + probs = self.dropout(probs) + + # => (batch, head, time1, d_k) + hidden_states = torch.matmul(probs, value) + + # => (batch, time1, hidden_size) + hidden_states = hidden_states.transpose(1, 2).reshape(batch_size, -1, self.num_heads * self.head_size) + hidden_states = self.linear_out(hidden_states) + + return hidden_states, probs + + # Copied from transformers.models.wav2vec2_conformer.modeling_wav2vec2_conformer.Wav2Vec2ConformerSelfAttention._apply_rotary_embedding + def _apply_rotary_embedding(self, hidden_states, relative_position_embeddings): + batch_size, sequence_length, hidden_size = hidden_states.size() + hidden_states = hidden_states.view(batch_size, sequence_length, self.num_heads, self.head_size) + + cos = relative_position_embeddings[0, :sequence_length, ...] + sin = relative_position_embeddings[1, :sequence_length, ...] + + # rotate hidden_states with rotary embeddings + hidden_states = hidden_states.transpose(0, 1) + rotated_states_begin = hidden_states[..., : self.head_size // 2] + rotated_states_end = hidden_states[..., self.head_size // 2 :] + rotated_states = torch.cat((-rotated_states_end, rotated_states_begin), dim=rotated_states_begin.ndim - 1) + hidden_states = (hidden_states * cos) + (rotated_states * sin) + hidden_states = hidden_states.transpose(0, 1) + + hidden_states = hidden_states.view(batch_size, sequence_length, self.num_heads * self.head_size) + + return hidden_states + + # Copied from transformers.models.wav2vec2_conformer.modeling_wav2vec2_conformer.Wav2Vec2ConformerSelfAttention._apply_relative_embeddings + def _apply_relative_embeddings(self, query, key, relative_position_embeddings): + # 1. project positional embeddings + # => (batch, head, 2*time1-1, d_k) + proj_relative_position_embeddings = self.linear_pos(relative_position_embeddings) + proj_relative_position_embeddings = proj_relative_position_embeddings.view( + relative_position_embeddings.size(0), -1, self.num_heads, self.head_size + ) + proj_relative_position_embeddings = proj_relative_position_embeddings.transpose(1, 2) + proj_relative_position_embeddings = proj_relative_position_embeddings.transpose(2, 3) + + # 2. Add bias to query + # => (batch, head, time1, d_k) + query = query.transpose(1, 2) + q_with_bias_u = (query + self.pos_bias_u).transpose(1, 2) + q_with_bias_v = (query + self.pos_bias_v).transpose(1, 2) + + # 3. attention score: first compute matrix a and matrix c + # as described in https://huggingface.co/papers/1901.02860 Section 3.3 + # => (batch, head, time1, time2) + scores_ac = torch.matmul(q_with_bias_u, key.transpose(-2, -1)) + + # 4. then compute matrix b and matrix d + # => (batch, head, time1, 2*time1-1) + scores_bd = torch.matmul(q_with_bias_v, proj_relative_position_embeddings) + + # 5. shift matrix b and matrix d + zero_pad = torch.zeros((*scores_bd.size()[:3], 1), device=scores_bd.device, dtype=scores_bd.dtype) + scores_bd_padded = torch.cat([zero_pad, scores_bd], dim=-1) + scores_bd_padded_shape = scores_bd.size()[:2] + (scores_bd.shape[3] + 1, scores_bd.shape[2]) + scores_bd_padded = scores_bd_padded.view(*scores_bd_padded_shape) + scores_bd = scores_bd_padded[:, :, 1:].view_as(scores_bd) + scores_bd = scores_bd[:, :, :, : scores_bd.size(-1) // 2 + 1] + + # 6. sum matrices + # => (batch, head, time1, time2) + scores = (scores_ac + scores_bd) / math.sqrt(self.head_size) + + return scores + + +class SeamlessM4TConformerEncoderLayer(GradientCheckpointingLayer): + """Conformer block based on https://huggingface.co/papers/2005.08100.""" + + # Copied from transformers.models.wav2vec2_conformer.modeling_wav2vec2_conformer.Wav2Vec2ConformerEncoderLayer.__init__ with Wav2Vec2->SeamlessM4T, attention_dropout->speech_encoder_dropout, torch.nn->nn + def __init__(self, config): + super().__init__() + embed_dim = config.hidden_size + dropout = config.speech_encoder_dropout + + # Feed-forward 1 + self.ffn1_layer_norm = nn.LayerNorm(embed_dim) + self.ffn1 = SeamlessM4TConformerFeedForward(config) + + # Self-Attention + self.self_attn_layer_norm = nn.LayerNorm(embed_dim) + self.self_attn_dropout = nn.Dropout(dropout) + self.self_attn = SeamlessM4TConformerSelfAttention(config) + + # Conformer Convolution + self.conv_module = SeamlessM4TConformerConvolutionModule(config) + + # Feed-forward 2 + self.ffn2_layer_norm = nn.LayerNorm(embed_dim) + self.ffn2 = SeamlessM4TConformerFeedForward(config) + self.final_layer_norm = nn.LayerNorm(embed_dim) + + def forward( + self, + hidden_states, + attention_mask: torch.Tensor | None = None, + relative_position_embeddings: torch.Tensor | None = None, + output_attentions: bool = False, + conv_attention_mask: torch.Tensor | None = None, + ): + # 1. Feed-Forward 1 layer + residual = hidden_states + hidden_states = self.ffn1_layer_norm(hidden_states) + hidden_states = self.ffn1(hidden_states) + hidden_states = hidden_states * 0.5 + residual + residual = hidden_states + + # 2. Self-Attention layer + hidden_states = self.self_attn_layer_norm(hidden_states) + hidden_states, attn_weigts = self.self_attn( + hidden_states=hidden_states, + attention_mask=attention_mask, + relative_position_embeddings=relative_position_embeddings, + output_attentions=output_attentions, + ) + hidden_states = self.self_attn_dropout(hidden_states) + hidden_states = hidden_states + residual + + # 3. Convolutional Layer + residual = hidden_states + hidden_states = self.conv_module(hidden_states, attention_mask=conv_attention_mask) + hidden_states = residual + hidden_states + + # 4. Feed-Forward 2 Layer + residual = hidden_states + hidden_states = self.ffn2_layer_norm(hidden_states) + hidden_states = self.ffn2(hidden_states) + hidden_states = hidden_states * 0.5 + residual + hidden_states = self.final_layer_norm(hidden_states) + + return hidden_states, attn_weigts + + +class SeamlessM4TConformerEncoder(nn.Module): + def __init__(self, config): + super().__init__() + self.config = config + + if config.position_embeddings_type == "relative": + self.embed_positions = SeamlessM4TConformerRelPositionalEmbedding(config) + elif config.position_embeddings_type == "rotary": + self.embed_positions = SeamlessM4TConformerRotaryPositionalEmbedding(config) + else: + self.embed_positions = None + + self.dropout = nn.Dropout(config.speech_encoder_dropout) + self.layers = nn.ModuleList( + [SeamlessM4TConformerEncoderLayer(config) for _ in range(config.speech_encoder_layers)] + ) + + self.layer_norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps) + + self.gradient_checkpointing = False + + def forward( + self, + hidden_states, + attention_mask=None, + output_attentions=False, + output_hidden_states=False, + return_dict=True, + ): + all_hidden_states = () if output_hidden_states else None + all_self_attentions = () if output_attentions else None + + conv_attention_mask = attention_mask + if attention_mask is not None: + # make sure padded tokens output 0 + hidden_states = hidden_states.masked_fill(~attention_mask.bool().unsqueeze(-1), 0.0) + # extend attention_mask + attention_mask = 1.0 - attention_mask[:, None, None, :].to(dtype=hidden_states.dtype) + attention_mask = attention_mask * torch.finfo(hidden_states.dtype).min + attention_mask = attention_mask.expand( + attention_mask.shape[0], 1, attention_mask.shape[-1], attention_mask.shape[-1] + ) + + hidden_states = self.dropout(hidden_states) + + if self.embed_positions is not None: + relative_position_embeddings = self.embed_positions(hidden_states) + else: + relative_position_embeddings = None + + synced_gpus = is_deepspeed_zero3_enabled() or is_fsdp_managed_module(self) + + for i, layer in enumerate(self.layers): + if output_hidden_states: + all_hidden_states = all_hidden_states + (hidden_states,) + + # add LayerDrop (see https://huggingface.co/papers/1909.11556 for description) + dropout_probability = torch.rand([]) + + skip_the_layer = self.training and dropout_probability < self.config.speech_encoder_layerdrop + if not skip_the_layer or synced_gpus: + # under fsdp or deepspeed zero3 all gpus must run in sync + layer_outputs = layer( + hidden_states, + attention_mask=attention_mask, + relative_position_embeddings=relative_position_embeddings, + output_attentions=output_attentions, + conv_attention_mask=conv_attention_mask, + ) + hidden_states = layer_outputs[0] + + if skip_the_layer: + layer_outputs = (None, None) + + if output_attentions: + all_self_attentions = all_self_attentions + (layer_outputs[1],) + + hidden_states = self.layer_norm(hidden_states) + if output_hidden_states: + all_hidden_states = all_hidden_states + (hidden_states,) + + if not return_dict: + return tuple(v for v in [hidden_states, all_hidden_states, all_self_attentions] if v is not None) + return BaseModelOutput( + last_hidden_state=hidden_states, + hidden_states=all_hidden_states, + attentions=all_self_attentions, + ) + + +class SeamlessM4TConformerAdapterLayer(nn.Module): + def __init__(self, config): + super().__init__() + self.config = config + + embed_dim = config.hidden_size + dropout = config.adaptor_dropout + + self.kernel_size = config.adaptor_kernel_size + self.stride = config.adaptor_stride + + # 1. residual convolution + self.residual_layer_norm = nn.LayerNorm(embed_dim) + self.residual_conv = nn.Conv1d( + embed_dim, + 2 * embed_dim, + self.kernel_size, + stride=self.stride, + padding=self.stride // 2, + ) + self.activation = nn.GLU(dim=1) + + # Self-Attention + self.self_attn_layer_norm = nn.LayerNorm(embed_dim) + self.self_attn_conv = nn.Conv1d( + embed_dim, + 2 * embed_dim, + self.kernel_size, + stride=self.stride, + padding=self.stride // 2, + ) + self.self_attn = SeamlessM4TConformerSelfAttention(config, use_position_embeddings=False) + self.self_attn_dropout = nn.Dropout(dropout) + + # Feed-forward + self.ffn_layer_norm = nn.LayerNorm(embed_dim) + self.ffn = SeamlessM4TConformerFeedForward(config, act_fn="relu", dropout=dropout) + + def _compute_sub_sample_lengths_from_attention_mask(self, attention_mask): + pad = self.kernel_size // 2 + seq_lens = attention_mask.size(1) - (1 - attention_mask.int()).sum(1) + + seq_lens = ((seq_lens + 2 * pad - self.kernel_size) / self.stride) + 1 + + return seq_lens.floor() + + def forward( + self, + hidden_states, + attention_mask: torch.Tensor | None = None, + output_attentions: bool = False, + ): + residual = self.residual_layer_norm(hidden_states) + + # Apply pooling to the residual to match the sequence length of the + # multi-head attention output. + # (batch, seq_len, feature_dim) -> (batch, feature_dim, seq_len) + residual = residual.transpose(1, 2) + residual = self.residual_conv(residual) + residual = self.activation(residual) + # (batch, feature_dim, seq_len) -> (batch, seq_len, feature_dim) + residual = residual.transpose(1, 2) + + hidden_states = self.self_attn_layer_norm(hidden_states) + # Apply pooling before feeding to the multihead-attention layer. + # (batch, seq_len, feature_dim) -> (batch, feature_dim, seq_len) + hidden_states = hidden_states.transpose(1, 2) + hidden_states = self.self_attn_conv(hidden_states) + hidden_states = self.activation(hidden_states) + # (batch, feature_dim, seq_len) -> (batch, seq_len, feature_dim) + hidden_states = hidden_states.transpose(1, 2) + + if attention_mask is not None: + sub_sampled_lengths = self._compute_sub_sample_lengths_from_attention_mask(attention_mask).to( + hidden_states.device + ) + attention_mask = _compute_new_attention_mask(hidden_states=hidden_states, seq_lens=sub_sampled_lengths) + attention_mask = create_bidirectional_mask( + config=self.config, + inputs_embeds=hidden_states, + attention_mask=attention_mask, + ) + + # The rest of the computation is identical to a vanilla Transformer + # encoder layer. + hidden_states, attn_weights = self.self_attn( + hidden_states, + attention_mask=attention_mask, + output_attentions=output_attentions, + ) + hidden_states = self.self_attn_dropout(hidden_states) + hidden_states = hidden_states + residual + + residual = hidden_states + + hidden_states = self.ffn_layer_norm(hidden_states) + hidden_states = self.ffn(hidden_states) + residual + + return hidden_states + + +class SeamlessM4TConformerAdapter(nn.Module): + def __init__(self, config): + super().__init__() + + self.layers = nn.ModuleList(SeamlessM4TConformerAdapterLayer(config) for _ in range(config.num_adapter_layers)) + + def forward(self, hidden_states, attention_mask): + # down project hidden_states if necessary + + for layer in self.layers: + hidden_states = layer(hidden_states, attention_mask) + + return hidden_states + + +############ TEXT / UNITS related code ################ + + +# Copied from transformers.models.m2m_100.modeling_m2m_100.M2M100ScaledWordEmbedding with M2M100->SeamlessM4T +class SeamlessM4TScaledWordEmbedding(nn.Embedding): + """ + This module overrides nn.Embeddings' forward by multiplying with embeddings scale. + """ + + def __init__(self, num_embeddings: int, embedding_dim: int, padding_idx: int, embed_scale: float | None = 1.0): + super().__init__(num_embeddings, embedding_dim, padding_idx) + self.embed_scale = embed_scale + + def forward(self, input_ids: torch.Tensor): + return super().forward(input_ids) * self.embed_scale + + +# Copied from transformers.models.m2m_100.modeling_m2m_100.M2M100SinusoidalPositionalEmbedding with M2M100->SeamlessM4T +class SeamlessM4TSinusoidalPositionalEmbedding(nn.Module): + """This module produces sinusoidal positional embeddings of any length.""" + + def __init__(self, num_positions: int, embedding_dim: int, padding_idx: int | None = None): + super().__init__() + self.offset = 2 + self.num_positions = num_positions + self.embedding_dim = embedding_dim + self.padding_idx = padding_idx + self.make_weights(num_positions + self.offset, embedding_dim, padding_idx) + + def make_weights(self, num_embeddings: int, embedding_dim: int, padding_idx: int | None = None): + emb_weights = self.get_embedding(num_embeddings, embedding_dim, padding_idx) + if hasattr(self, "weights"): + # in forward put the weights on the correct dtype and device of the param + emb_weights = emb_weights.to(dtype=self.weights.dtype, device=self.weights.device) + + self.register_buffer("weights", emb_weights, persistent=False) + + @staticmethod + def get_embedding(num_embeddings: int, embedding_dim: int, padding_idx: int | None = None): + """ + Build sinusoidal embeddings. + + This matches the implementation in tensor2tensor, but differs slightly from the description in Section 3.5 of + "Attention Is All You Need". + """ + half_dim = embedding_dim // 2 + emb = math.log(10000) / (half_dim - 1) + emb = torch.exp(torch.arange(half_dim, dtype=torch.int64).float() * -emb) + emb = torch.arange(num_embeddings, dtype=torch.int64).float().unsqueeze(1) * emb.unsqueeze(0) + emb = torch.cat([torch.sin(emb), torch.cos(emb)], dim=1).view(num_embeddings, -1) + if embedding_dim % 2 == 1: + # zero pad + emb = torch.cat([emb, torch.zeros(num_embeddings, 1)], dim=1) + if padding_idx is not None: + emb[padding_idx, :] = 0 + + return emb.to(torch.get_default_dtype()) + + @torch.no_grad() + def forward( + self, + input_ids: torch.Tensor | None = None, + inputs_embeds: torch.Tensor | None = None, + past_key_values_length: int = 0, + ): + if input_ids is not None: + bsz, seq_len = input_ids.size() + # Create the position ids from the input token ids. Any padded tokens remain padded. + position_ids = self.create_position_ids_from_input_ids( + input_ids, self.padding_idx, past_key_values_length + ).to(input_ids.device) + else: + bsz, seq_len = inputs_embeds.size()[:-1] + position_ids = self.create_position_ids_from_inputs_embeds( + inputs_embeds, past_key_values_length, self.padding_idx + ) + + # expand embeddings if needed + max_pos = self.padding_idx + 1 + seq_len + past_key_values_length + if max_pos > self.weights.size(0): + self.make_weights(max_pos + self.offset, self.embedding_dim, self.padding_idx) + + return self.weights.index_select(0, position_ids.view(-1)).view(bsz, seq_len, self.weights.shape[-1]).detach() + + @staticmethod + def create_position_ids_from_inputs_embeds(inputs_embeds, past_key_values_length, padding_idx): + """ + We are provided embeddings directly. We cannot infer which are padded so just generate sequential position ids. + + Args: + inputs_embeds: torch.Tensor + + Returns: torch.Tensor + """ + input_shape = inputs_embeds.size()[:-1] + sequence_length = input_shape[1] + + position_ids = torch.arange( + padding_idx + 1, sequence_length + padding_idx + 1, dtype=torch.long, device=inputs_embeds.device + ) + return position_ids.unsqueeze(0).expand(input_shape).contiguous() + past_key_values_length + + @staticmethod + # Copied from transformers.models.roberta.modeling_roberta.RobertaEmbeddings.create_position_ids_from_input_ids + def create_position_ids_from_input_ids(input_ids, padding_idx, past_key_values_length=0): + """ + Replace non-padding symbols with their position numbers. Position numbers begin at padding_idx+1. Padding symbols + are ignored. This is modified from fairseq's `utils.make_positions`. + + Args: + x: torch.Tensor x: + + Returns: torch.Tensor + """ + # The series of casts and type-conversions here are carefully balanced to both work with ONNX export and XLA. + mask = input_ids.ne(padding_idx).int() + incremental_indices = (torch.cumsum(mask, dim=1).type_as(mask) + past_key_values_length) * mask + return incremental_indices.long() + padding_idx + + +class SeamlessM4TAttention(nn.Module): + """Multi-headed attention from 'Attention Is All You Need' paper""" + + # Copied from transformers.models.bart.modeling_bart.BartAttention.__init__ with Bart->SeamlessM4T + def __init__( + self, + embed_dim: int, + num_heads: int, + dropout: float = 0.0, + is_decoder: bool = False, + bias: bool = True, + is_causal: bool = False, + config: SeamlessM4TConfig | None = None, + layer_idx: int | None = None, + ): + super().__init__() + self.embed_dim = embed_dim + self.num_heads = num_heads + self.dropout = dropout + self.head_dim = embed_dim // num_heads + self.config = config + + if (self.head_dim * num_heads) != self.embed_dim: + raise ValueError( + f"embed_dim must be divisible by num_heads (got `embed_dim`: {self.embed_dim}" + f" and `num_heads`: {num_heads})." + ) + self.scaling = self.head_dim**-0.5 + self.is_decoder = is_decoder + self.is_causal = is_causal + self.layer_idx = layer_idx + if layer_idx is None and self.is_decoder: + logger.warning_once( + f"Instantiating a decoder {self.__class__.__name__} without passing `layer_idx` is not recommended and " + "will lead to errors during the forward call, if caching is used. Please make sure to provide a `layer_idx` " + "when creating this class." + ) + + self.k_proj = nn.Linear(embed_dim, embed_dim, bias=bias) + self.v_proj = nn.Linear(embed_dim, embed_dim, bias=bias) + self.q_proj = nn.Linear(embed_dim, embed_dim, bias=bias) + self.out_proj = nn.Linear(embed_dim, embed_dim, bias=bias) + + def forward( + self, + hidden_states: torch.Tensor, + encoder_hidden_states: torch.Tensor | None = None, + past_key_values: Cache | None = None, + attention_mask: torch.Tensor | None = None, + output_attentions: bool = False, + cache_position: torch.Tensor | None = None, + ) -> tuple[torch.Tensor, torch.Tensor | None, tuple[torch.Tensor] | None]: + """Input shape: Batch x Time x Channel""" + + # if encoder_hidden_states are provided this layer is used as a cross-attention layer + # for the decoder + is_cross_attention = encoder_hidden_states is not None + + bsz, tgt_len, _ = hidden_states.size() + + # get query proj + query_states = self.q_proj(hidden_states) * self.scaling + + is_updated = False + if past_key_values is not None: + if isinstance(past_key_values, EncoderDecoderCache): + is_updated = past_key_values.is_updated.get(self.layer_idx) + if is_cross_attention: + # after the first generated id, we can subsequently re-use all key/value_states from cache + curr_past_key_values = past_key_values.cross_attention_cache + else: + curr_past_key_values = past_key_values.self_attention_cache + else: + curr_past_key_values = past_key_values + + current_states = encoder_hidden_states if is_cross_attention else hidden_states + if is_cross_attention and past_key_values is not None and is_updated: + # reuse k,v, cross_attentions + key_states = curr_past_key_values.layers[self.layer_idx].keys + value_states = curr_past_key_values.layers[self.layer_idx].values + else: + key_states = self.k_proj(current_states) + value_states = self.v_proj(current_states) + key_states = key_states.view(bsz, -1, self.num_heads, self.head_dim).transpose(1, 2) + value_states = value_states.view(bsz, -1, self.num_heads, self.head_dim).transpose(1, 2) + + if past_key_values is not None: + # save all key/value_states to cache to be re-used for fast auto-regressive generation + cache_position = cache_position if not is_cross_attention else None + key_states, value_states = curr_past_key_values.update( + key_states, value_states, self.layer_idx, {"cache_position": cache_position} + ) + # set flag that curr layer for cross-attn is already updated so we can re-use in subsequent calls + if is_cross_attention and isinstance(past_key_values, EncoderDecoderCache): + past_key_values.is_updated[self.layer_idx] = True + + proj_shape = (bsz * self.num_heads, -1, self.head_dim) + query_states = query_states.view(bsz, tgt_len, self.num_heads, self.head_dim).transpose(1, 2) + query_states = query_states.reshape(*proj_shape) + key_states = key_states.reshape(*proj_shape) + value_states = value_states.reshape(*proj_shape) + + src_len = key_states.size(1) + attn_weights = torch.bmm(query_states, key_states.transpose(1, 2)) + + if attn_weights.size() != (bsz * self.num_heads, tgt_len, src_len): + raise ValueError( + f"Attention weights should be of size {(bsz * self.num_heads, tgt_len, src_len)}, but is" + f" {attn_weights.size()}" + ) + + if attention_mask is not None: + if attention_mask.size() != (bsz, 1, tgt_len, src_len): + raise ValueError( + f"Attention mask should be of size {(bsz, 1, tgt_len, src_len)}, but is {attention_mask.size()}" + ) + attn_weights = attn_weights.view(bsz, self.num_heads, tgt_len, src_len) + attention_mask + attn_weights = attn_weights.view(bsz * self.num_heads, tgt_len, src_len) + + attn_weights = nn.functional.softmax(attn_weights, dim=-1) + + if output_attentions: + # this operation is a bit awkward, but it's required to + # make sure that attn_weights keeps its gradient. + # In order to do so, attn_weights have to be reshaped + # twice and have to be reused in the following + attn_weights_reshaped = attn_weights.view(bsz, self.num_heads, tgt_len, src_len) + attn_weights = attn_weights_reshaped.view(bsz * self.num_heads, tgt_len, src_len) + else: + attn_weights_reshaped = None + + attn_probs = nn.functional.dropout(attn_weights, p=self.dropout, training=self.training) + + attn_output = torch.bmm(attn_probs, value_states) + + if attn_output.size() != (bsz * self.num_heads, tgt_len, self.head_dim): + raise ValueError( + f"`attn_output` should be of size {(bsz * self.num_heads, tgt_len, self.head_dim)}, but is" + f" {attn_output.size()}" + ) + + attn_output = attn_output.view(bsz, self.num_heads, tgt_len, self.head_dim) + attn_output = attn_output.transpose(1, 2) + + # Use the `embed_dim` from the config (stored in the class) rather than `hidden_state` because `attn_output` can be + # partitioned across GPUs when using tensor-parallelism. + attn_output = attn_output.reshape(bsz, tgt_len, self.embed_dim) + + attn_output = self.out_proj(attn_output) + + return attn_output, attn_weights_reshaped + + +# Copied from transformers.models.nllb_moe.modeling_nllb_moe.NllbMoeDenseActDense with NllbMoe->SeamlessM4T,DenseActDense->FeedForwardNetwork, d_model->hidden_size +class SeamlessM4TFeedForwardNetwork(nn.Module): + def __init__(self, config: SeamlessM4TConfig, ffn_dim: int): + super().__init__() + self.fc1 = nn.Linear(config.hidden_size, ffn_dim) + self.fc2 = nn.Linear(ffn_dim, config.hidden_size) + self.dropout = nn.Dropout(config.activation_dropout) + self.act = ACT2FN[config.activation_function] + + def forward(self, hidden_states: torch.Tensor): + hidden_states = self.fc1(hidden_states) + hidden_states = self.act(hidden_states) + hidden_states = self.dropout(hidden_states) + if ( + isinstance(self.fc2.weight, torch.Tensor) + and hidden_states.dtype != self.fc2.weight.dtype + and (self.fc2.weight.dtype != torch.int8 and self.fc2.weight.dtype != torch.uint8) + ): + hidden_states = hidden_states.to(self.fc2.weight.dtype) + hidden_states = self.fc2(hidden_states) + return hidden_states + + +class SeamlessM4TEncoderLayer(GradientCheckpointingLayer): + def __init__(self, config: SeamlessM4TConfig, encoder_ffn_dim=None, encoder_attention_heads=None): + super().__init__() + encoder_ffn_dim = config.encoder_ffn_dim if encoder_ffn_dim is None else encoder_ffn_dim + encoder_attention_heads = ( + config.encoder_attention_heads if encoder_attention_heads is None else encoder_attention_heads + ) + + self.embed_dim = config.hidden_size + self.self_attn = SeamlessM4TAttention( + embed_dim=self.embed_dim, + num_heads=encoder_attention_heads, + dropout=config.attention_dropout, + ) + self.attn_dropout = nn.Dropout(config.dropout) + self.self_attn_layer_norm = nn.LayerNorm(self.embed_dim) + + self.ffn = SeamlessM4TFeedForwardNetwork(config, ffn_dim=encoder_ffn_dim) + + self.ffn_layer_norm = nn.LayerNorm(config.hidden_size) + self.ffn_dropout = nn.Dropout(config.activation_dropout) + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.Tensor, + output_attentions: bool = False, + ) -> torch.Tensor: + """ + Args: + hidden_states (`torch.FloatTensor`): + input to the layer of shape `(batch, seq_len, embed_dim)` + attention_mask (`torch.FloatTensor`): + attention mask of size `(batch, 1, tgt_len, src_len)` where padding elements are indicated by very + large negative values. + """ + residual = hidden_states + hidden_states = self.self_attn_layer_norm(hidden_states) + hidden_states, attn_weights = self.self_attn( + hidden_states=hidden_states, + attention_mask=attention_mask, + output_attentions=output_attentions, + ) + hidden_states = self.attn_dropout(hidden_states) + hidden_states = residual + hidden_states + + residual = hidden_states + + hidden_states = self.ffn_layer_norm(hidden_states) + + hidden_states = self.ffn(hidden_states) + hidden_states = self.ffn_dropout(hidden_states) + + hidden_states = residual + hidden_states + + outputs = (hidden_states,) + + if output_attentions: + outputs += (attn_weights,) + + return outputs + + +class SeamlessM4TDecoderLayer(GradientCheckpointingLayer): + def __init__(self, config: SeamlessM4TConfig, decoder_ffn_dim=None, decoder_attention_heads=None, layer_idx=None): + super().__init__() + decoder_ffn_dim = config.decoder_ffn_dim if decoder_ffn_dim is None else decoder_ffn_dim + decoder_attention_heads = ( + config.decoder_attention_heads if decoder_attention_heads is None else decoder_attention_heads + ) + + self.embed_dim = config.hidden_size + self.self_attn = SeamlessM4TAttention( + embed_dim=self.embed_dim, + num_heads=decoder_attention_heads, + dropout=config.attention_dropout, + is_decoder=True, + layer_idx=layer_idx, + ) + self.dropout = config.dropout + self.activation_fn = ACT2FN[config.activation_function] + self.attn_dropout = nn.Dropout(config.dropout) + + self.self_attn_layer_norm = nn.LayerNorm(self.embed_dim) + self.cross_attention = SeamlessM4TAttention( + self.embed_dim, + decoder_attention_heads, + config.attention_dropout, + is_decoder=True, + layer_idx=layer_idx, + ) + self.cross_attention_layer_norm = nn.LayerNorm(self.embed_dim) + + self.ffn = SeamlessM4TFeedForwardNetwork(config, ffn_dim=decoder_ffn_dim) + + self.ffn_layer_norm = nn.LayerNorm(config.hidden_size) + self.ffn_dropout = nn.Dropout(config.activation_dropout) + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.Tensor | None = None, + encoder_hidden_states: torch.Tensor | None = None, + encoder_attention_mask: torch.Tensor | None = None, + past_key_values: Cache | None = None, + output_attentions: bool | None = False, + use_cache: bool | None = True, + cache_position: torch.Tensor | None = None, + ) -> torch.Tensor: + """ + Args: + hidden_states (`torch.FloatTensor`): + input to the layer of shape `(batch, seq_len, embed_dim)` + attention_mask (`torch.FloatTensor`): + attention mask of size `(batch, 1, tgt_len, src_len)` where padding elements are indicated by very + large negative values. + encoder_hidden_states (`torch.FloatTensor`): + cross attention input to the layer of shape `(batch, seq_len, embed_dim)` + encoder_attention_mask (`torch.FloatTensor`): + encoder attention mask of size `(batch, 1, tgt_len, src_len)` where padding elements are indicated by + very large negative values. + past_key_values (`Cache`): + cached past key and value projection states + output_attentions (`bool`, *optional*): + Whether or not to return the attentions tensors of all attention layers. See `attentions` under + returned tensors for more detail. + """ + residual = hidden_states + hidden_states = self.self_attn_layer_norm(hidden_states) + + # Self Attention + hidden_states, self_attn_weights = self.self_attn( + hidden_states=hidden_states, + past_key_values=past_key_values, + attention_mask=attention_mask, + output_attentions=output_attentions, + cache_position=cache_position, + ) + hidden_states = self.attn_dropout(hidden_states) + hidden_states = residual + hidden_states + + # Cross-Attention Block + cross_attn_weights = None + if encoder_hidden_states is not None: + residual = hidden_states + hidden_states = self.cross_attention_layer_norm(hidden_states) + + hidden_states, cross_attn_weights = self.cross_attention( + hidden_states=hidden_states, + encoder_hidden_states=encoder_hidden_states, + past_key_values=past_key_values, + attention_mask=encoder_attention_mask, + output_attentions=output_attentions, + cache_position=cache_position, + ) + hidden_states = self.attn_dropout(hidden_states) + hidden_states = residual + hidden_states + + # Fully Connected + residual = hidden_states + + hidden_states = self.ffn_layer_norm(hidden_states) + + hidden_states = self.ffn(hidden_states) + hidden_states = self.ffn_dropout(hidden_states) + + hidden_states = residual + hidden_states + + return hidden_states, self_attn_weights, cross_attn_weights + + +############ SUB-MODELS related code ################ + + +@auto_docstring +class SeamlessM4TPreTrainedModel(PreTrainedModel): + config: SeamlessM4TConfig + base_model_prefix = "seamless_m4t" + supports_gradient_checkpointing = True + _no_split_modules = ["SeamlessM4TEncoderLayer", "SeamlessM4TDecoderLayer", "SeamlessM4TConformerEncoderLayer"] + + @torch.no_grad() + def _init_weights(self, module: nn.Module): + """Initialize the weights""" + std = self.config.initializer_range + if isinstance(module, nn.Linear): + init.normal_(module.weight, mean=0.0, std=std) + if module.bias is not None: + init.zeros_(module.bias) + elif isinstance(module, nn.Embedding): + init.normal_(module.weight, mean=0.0, std=std) + # Here we need the check explicitly, as we slice the weight in the `zeros_` call, so it looses the flag + if module.padding_idx is not None and not getattr(module.weight, "_is_hf_initialized", False): + init.zeros_(module.weight[module.padding_idx]) + elif isinstance(module, SeamlessM4TConformerSelfAttention): + if hasattr(module, "pos_bias_u"): + init.xavier_uniform_(module.pos_bias_u) + if hasattr(module, "pos_bias_v"): + init.xavier_uniform_(module.pos_bias_v) + elif isinstance(module, SeamlessM4TConformerPositionalConvEmbedding): + init.normal_( + module.conv.weight, + mean=0, + std=2 * math.sqrt(1 / (module.conv.kernel_size[0] * module.conv.in_channels)), + ) + init.constant_(module.conv.bias, 0) + elif isinstance(module, SeamlessM4TConformerFeatureProjection): + k = math.sqrt(1 / module.projection.in_features) + init.uniform_(module.projection.weight, a=-k, b=k) + init.uniform_(module.projection.bias, a=-k, b=k) + elif isinstance(module, (nn.LayerNorm, nn.BatchNorm1d)): + init.zeros_(module.bias) + init.ones_(module.weight) + if getattr(module, "running_mean", None) is not None: + init.zeros_(module.running_mean) + init.ones_(module.running_var) + init.zeros_(module.num_batches_tracked) + elif isinstance(module, nn.Conv1d): + init.kaiming_normal_(module.weight) + if module.bias is not None: + k = math.sqrt(module.groups / (module.in_channels * module.kernel_size[0])) + init.uniform_(module.bias, a=-k, b=k) + elif isinstance(module, SeamlessM4TSinusoidalPositionalEmbedding): + emb_weights = module.get_embedding( + module.num_positions + module.offset, module.embedding_dim, module.padding_idx + ) + init.copy_(module.weights, emb_weights) + elif isinstance(module, SeamlessM4TConformerRotaryPositionalEmbedding): + dim = self.config.hidden_size // self.config.speech_encoder_attention_heads + base = self.config.rotary_embedding_base + inv_freq = 1.0 / (base ** (torch.arange(0, dim, 2, dtype=torch.int64).float() / dim)) + init.copy_(module.inv_freq, inv_freq) + elif isinstance(module, SeamlessM4TConformerRelPositionalEmbedding): + init.copy_(module.pe, module.extend_pe(torch.tensor(0.0).expand(1, module.max_len))) + + def _compute_sub_sample_lengths_from_attention_mask(self, attention_mask): + kernel_size, stride = self.config.adaptor_kernel_size, self.config.adaptor_stride + pad = kernel_size // 2 + seq_lens = attention_mask.size(1) - (1 - attention_mask.int()).sum(1) + + seq_lens = ((seq_lens + 2 * pad - kernel_size) / stride) + 1 + + return seq_lens.floor() + + def compute_last_hidden_states_per_sample( + self, + hidden_states: tuple[tuple[torch.Tensor]], + beam_indices: torch.Tensor | None = None, + ) -> torch.Tensor: + """ + Computes the last hidden states. + + Parameters: + hidden_states (`tuple[tuple[torch.Tensor]]`): + The generated hidden states. Tuple (one element for each generated token) of tuples (one element for + each layer of the decoder) of torch.FloatTensor of shape (batch_size*num_beams*num_return_sequences, + generated_length, hidden_size). + beam_indices (`torch.LongTensor`, *optional*): + Beam indices of generated token id at each generation step. `torch.LongTensor` of shape + `(batch_size*num_return_sequences, sequence_length)`. Only required if a `num_beams>1` at + generate-time. + + Return: + `torch.Tensor`: A `torch.Tensor` of shape `(batch_size*num_return_sequences, sequence_length, hidden_size)` + containing + the last hidden states. + ```""" + # 1. First, let's compute last_hidden_states from hidden_states. + # For each generation step, takes the hidden state from the last layer. + # shape: (batch_size*vocab_size*num_return_sequences, # generation_steps, hidden_dim) + last_hidden_states = torch.concat([hidden_states[-1] for hidden_states in hidden_states], dim=1) + + # 2. In absence of `beam_indices`, we can assume that we come from e.g. greedy search, which is equivalent + # to a beam search approach were the first (and only) beam is always selected + # in that case, return directly last_hidden_states + if beam_indices is None: + return last_hidden_states + + # 3. cut beam_indices to longest beam length + beam_indices_mask = beam_indices < 0 + max_beam_length = (1 - beam_indices_mask.long()).sum(-1).max() + beam_indices = beam_indices.clone()[:, :max_beam_length] + beam_indices_mask = beam_indices_mask[:, :max_beam_length] + + # 4. Set indices of beams that finished early to 0; such indices will be masked correctly afterwards anyways + beam_indices[beam_indices_mask] = 0 + + # 5. expand beam_indices to last_hidden_states dim + beam_indices = beam_indices.unsqueeze(-1) + beam_indices = beam_indices.expand(-1, -1, last_hidden_states.shape[-1]) + + # 6. select the right candidate for each beam + # in other words, new_last_hidden_states[i,j,k] = last_hidden_states[beam_indices[i,j,k], j, k] for all i, j, k + last_hidden_states = torch.gather(last_hidden_states, 0, beam_indices) + + return last_hidden_states + + +@auto_docstring( + custom_intro=""" + Transformer speech encoder consisting of *config.speech_encoder_layers* conformer self attention layers. + Each layer is a [`SeamlessM4TConformerEncoderLayer`]. + """ +) +class SeamlessM4TSpeechEncoder(SeamlessM4TPreTrainedModel): + main_input_name = "input_features" + input_modalities = "audio" + + def __init__(self, config: SeamlessM4TConfig): + super().__init__(config) + + self.feature_projection = SeamlessM4TConformerFeatureProjection(config) + self.encoder = SeamlessM4TConformerEncoder(config) + self.intermediate_ffn = SeamlessM4TConformerFeedForward(config, act_fn="relu", dropout=0.0) + self.adapter = SeamlessM4TConformerAdapter(config) if config.add_adapter else None + self.inner_layer_norm = nn.LayerNorm(config.hidden_size) + + # Initialize weights and apply final processing + self.post_init() + + def forward( + self, + input_features: torch.Tensor | None, + attention_mask: torch.Tensor | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + **kwargs, + ) -> tuple | Wav2Vec2BaseModelOutput: + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + if input_features is None: + raise ValueError( + """Both `input_features` and `inputs_embeds` are `None` in `SeamlessM4TSpeechEncoder.forward`. + Make sure one of them is not `None`.""" + ) + + hidden_states = self.feature_projection(input_features) + + encoder_outputs = self.encoder( + hidden_states, + attention_mask=attention_mask, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + + hidden_states = encoder_outputs[0] + + expanded_hidden_states = self.intermediate_ffn(hidden_states) + hidden_states = hidden_states + 0.5 * expanded_hidden_states + + if self.adapter is not None: + hidden_states = self.adapter(hidden_states, attention_mask=attention_mask) + + hidden_states = self.inner_layer_norm(hidden_states) + + if not return_dict: + return (hidden_states,) + encoder_outputs[1:] + + return Wav2Vec2BaseModelOutput( + last_hidden_state=hidden_states, + hidden_states=encoder_outputs.hidden_states, + attentions=encoder_outputs.attentions, + ) + + +# inspired from MBart and NllbMoe +@auto_docstring( + custom_intro=""" + Transformer encoder consisting of *config.encoder_layers* self attention layers. Each layer is a [`SeamlessM4TEncoderLayer`]. + """ +) +class SeamlessM4TEncoder(SeamlessM4TPreTrainedModel): + def __init__( + self, + config: SeamlessM4TConfig, + embed_tokens: nn.Embedding | None = None, + is_t2u_encoder: bool = False, + ): + r""" + embed_tokens (`nn.Embedding`, *optional*): + Input embedding + is_t2u_encoder (`bool`, *optional*, defaults to `False`): + indicates if it belongs to the text-to-units model, in which case it won't have input embeddings + """ + super().__init__(config) + + self.dropout = config.dropout + self.layerdrop = config.encoder_layerdrop + self.padding_idx = config.pad_token_id + embed_dim = config.hidden_size + + self.is_t2u_encoder = is_t2u_encoder + self.max_source_positions = config.max_position_embeddings + + if not self.is_t2u_encoder: + embed_scale = math.sqrt(embed_dim) if config.scale_embedding else 1.0 + + self.embed_tokens = SeamlessM4TScaledWordEmbedding( + config.vocab_size, embed_dim, self.padding_idx, embed_scale=embed_scale + ) + + if embed_tokens is not None: + self.embed_tokens.weight = embed_tokens.weight + + self.embed_positions = SeamlessM4TSinusoidalPositionalEmbedding( + self.max_source_positions, + embed_dim, + self.padding_idx, + ) + + layers = [] + for _ in range(config.encoder_layers): + layers.append( + SeamlessM4TEncoderLayer( + config, + encoder_attention_heads=config.encoder_attention_heads, + encoder_ffn_dim=config.encoder_ffn_dim, + ) + ) + + self.layers = nn.ModuleList(layers) + + self.layer_norm = nn.LayerNorm(config.hidden_size) + + self.gradient_checkpointing = False + # Initialize weights and apply final processing + self.post_init() + + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.Tensor | None = None, + inputs_embeds: torch.FloatTensor | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + **kwargs, + ) -> tuple | BaseModelOutput: + r""" + Args: + input_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`): + Indices of input sequence tokens in the vocabulary. Padding will be ignored by default should you + provide it. + + Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and + [`PreTrainedTokenizer.__call__`] for details. + + [What are input IDs?](../glossary#input-ids) + attention_mask (`torch.Tensor` of shape `(batch_size, sequence_length)`, *optional*): + Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`: + + - 1 for tokens that are **not masked**, + - 0 for tokens that are **masked**. + + [What are attention masks?](../glossary#attention-mask) + inputs_embeds (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*): + Optionally, instead of passing `input_ids` you can choose to directly pass an embedded representation. + This is useful if you want more control over how to convert `input_ids` indices into associated vectors + than the model's internal embedding lookup matrix. + output_attentions (`bool`, *optional*): + Whether or not to return the attentions tensors of all attention layers. See `attentions` under + returned tensors for more detail. + output_hidden_states (`bool`, *optional*): + Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors + for more detail. + return_dict (`bool`, *optional*): + Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple. + """ + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + if input_ids is not None and self.is_t2u_encoder: + raise ValueError( + "You cannot pass input_ids to the encoder of the text_to_units model. Pass inputs_embeds instead." + ) + + # retrieve input_ids and inputs_embeds + if input_ids is not None and inputs_embeds is not None: + raise ValueError("You cannot specify both input_ids and inputs_embeds at the same time") + elif input_ids is not None: + input = input_ids + input_shape = input.shape + input_ids = input_ids.view(-1, input_shape[-1]) + elif inputs_embeds is not None: + input = inputs_embeds[:, :, -1] + else: + raise ValueError("You have to specify either input_ids or inputs_embeds") + + if inputs_embeds is None: + inputs_embeds = self.embed_tokens(input_ids) + + if not self.is_t2u_encoder: + embed_pos = self.embed_positions(input) + + hidden_states = inputs_embeds + embed_pos.to(inputs_embeds.device) + else: + hidden_states = inputs_embeds + + hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training) + + # expand attention_mask + if attention_mask is not None: + attention_mask = create_bidirectional_mask( + config=self.config, + inputs_embeds=inputs_embeds, + attention_mask=attention_mask, + ) + + encoder_states = () if output_hidden_states else None + all_attentions = () if output_attentions else None + + for idx, encoder_layer in enumerate(self.layers): + if output_hidden_states: + encoder_states = encoder_states + (hidden_states,) + # add LayerDrop (see https://huggingface.co/papers/1909.11556 for description) + to_drop = False + if self.training: + dropout_probability = torch.rand([]) + if dropout_probability < self.layerdrop: # skip the layer + to_drop = True + + if to_drop: + layer_outputs = (None, None) + else: + layer_outputs = encoder_layer( + hidden_states, + attention_mask, + output_attentions=output_attentions, + ) + + hidden_states = layer_outputs[0] + + if output_attentions: + all_attentions = all_attentions + (layer_outputs[1],) + + hidden_states = self.layer_norm(hidden_states) + + if output_hidden_states: + encoder_states = encoder_states + (hidden_states,) + + if not return_dict: + return tuple(v for v in [hidden_states, encoder_states, all_attentions] if v is not None) + return BaseModelOutput( + last_hidden_state=hidden_states, hidden_states=encoder_states, attentions=all_attentions + ) + + +@auto_docstring( + custom_intro=""" + Transformer decoder consisting of *config.decoder_layers* layers. Each layer is a [`SeamlessM4TDecoderLayer`]. + """ +) +class SeamlessM4TDecoder(SeamlessM4TPreTrainedModel): + def __init__( + self, + config: SeamlessM4TConfig, + embed_tokens: nn.Embedding | None = None, + ): + r""" + embed_tokens (`nn.Embedding`, *optional*): + Input embedding + """ + super().__init__(config) + self.dropout = config.dropout + self.layerdrop = config.decoder_layerdrop + self.padding_idx = config.pad_token_id + self.vocab_size = config.vocab_size + self.max_target_positions = config.max_position_embeddings + embed_scale = math.sqrt(config.hidden_size) if config.scale_embedding else 1.0 + + if embed_tokens is not None: + # if embed_tokens defined, use its shape instead + self.embed_tokens = SeamlessM4TScaledWordEmbedding( + embed_tokens.num_embeddings, embed_tokens.embedding_dim, self.padding_idx, embed_scale=embed_scale + ) + self.embed_tokens.weight = embed_tokens.weight + else: + self.embed_tokens = SeamlessM4TScaledWordEmbedding( + self.vocab_size, config.hidden_size, self.padding_idx, embed_scale=embed_scale + ) + + self.embed_positions = SeamlessM4TSinusoidalPositionalEmbedding( + self.max_target_positions, + config.hidden_size, + padding_idx=self.padding_idx, + ) + + layers = [] + for i in range(config.decoder_layers): + layers.append( + SeamlessM4TDecoderLayer( + config, + decoder_attention_heads=config.decoder_attention_heads, + decoder_ffn_dim=config.decoder_ffn_dim, + layer_idx=i, + ) + ) + self.layers = nn.ModuleList(layers) + self.layer_norm = nn.LayerNorm(config.hidden_size) + + self.gradient_checkpointing = False + # Initialize weights and apply final processing + self.post_init() + + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.Tensor | None = None, + encoder_hidden_states: torch.FloatTensor | None = None, + encoder_attention_mask: torch.LongTensor | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.FloatTensor | None = None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + cache_position: torch.Tensor | None = None, + **kwargs, + ) -> tuple | BaseModelOutputWithPastAndCrossAttentions: + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + use_cache = use_cache if use_cache is not None else self.config.use_cache + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + # retrieve input_ids and inputs_embeds + if input_ids is not None and inputs_embeds is not None: + raise ValueError("You cannot specify both decoder_input_ids and decoder_inputs_embeds at the same time") + elif input_ids is not None: + input = input_ids + input_shape = input.size() + input_ids = input_ids.view(-1, input_shape[-1]) + elif inputs_embeds is not None: + input_shape = inputs_embeds.size()[:-1] + input = inputs_embeds[:, :, -1] + else: + raise ValueError("You have to specify either decoder_input_ids or decoder_inputs_embeds") + + if inputs_embeds is None: + inputs_embeds = self.embed_tokens(input_ids) + + if self.gradient_checkpointing and self.training: + if use_cache: + logger.warning_once( + "`use_cache=True` is incompatible with gradient checkpointing`. Setting `use_cache=False`..." + ) + use_cache = False + + # initialize `past_key_values` + if use_cache and past_key_values is None: + past_key_values = EncoderDecoderCache(DynamicCache(config=self.config), DynamicCache(config=self.config)) + + past_key_values_length = past_key_values.get_seq_length() if past_key_values is not None else 0 + if cache_position is None: + cache_position = torch.arange( + past_key_values_length, past_key_values_length + inputs_embeds.shape[1], device=inputs_embeds.device + ) + + attention_mask = create_causal_mask( + config=self.config, + inputs_embeds=inputs_embeds, + attention_mask=attention_mask, + cache_position=cache_position, + past_key_values=past_key_values, + ) + + # expand encoder attention mask + if encoder_hidden_states is not None and encoder_attention_mask is not None: + encoder_attention_mask = create_bidirectional_mask( + config=self.config, + inputs_embeds=inputs_embeds, + attention_mask=encoder_attention_mask, + encoder_hidden_states=encoder_hidden_states, + ) + + # embed positions + positions = self.embed_positions(input, past_key_values_length=past_key_values_length) + + hidden_states = inputs_embeds + positions.to(inputs_embeds.device) + + hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training) + + # decoder layers + all_hidden_states = () if output_hidden_states else None + all_self_attns = () if output_attentions else None + all_cross_attentions = () if (output_attentions and encoder_hidden_states is not None) else None + + for idx, decoder_layer in enumerate(self.layers): + # add LayerDrop (see https://huggingface.co/papers/1909.11556 for description) + if output_hidden_states: + all_hidden_states += (hidden_states,) + if self.training: + dropout_probability = torch.rand([]) + if dropout_probability < self.layerdrop: + continue + + layer_outputs = decoder_layer( + hidden_states, + attention_mask, + encoder_hidden_states, # as a positional argument for gradient checkpointing + encoder_attention_mask=encoder_attention_mask, + past_key_values=past_key_values, + output_attentions=output_attentions, + use_cache=use_cache, + cache_position=cache_position, + ) + hidden_states = layer_outputs[0] + if output_attentions: + all_self_attns += (layer_outputs[1],) + + if encoder_hidden_states is not None: + all_cross_attentions += (layer_outputs[2],) + + hidden_states = self.layer_norm(hidden_states) + + # add hidden states from the last decoder layer + if output_hidden_states: + all_hidden_states += (hidden_states,) + + if not return_dict: + return tuple( + v + for v in [hidden_states, past_key_values, all_hidden_states, all_self_attns, all_cross_attentions] + if v is not None + ) + return BaseModelOutputWithPastAndCrossAttentions( + last_hidden_state=hidden_states, + past_key_values=past_key_values, + hidden_states=all_hidden_states, + attentions=all_self_attns, + cross_attentions=all_cross_attentions, + ) + + +@auto_docstring( + custom_intro=""" + Transformer bare text-to-unit encoder-decoder. The encoder is a [`SeamlessM4TEncoder`] without embeddings and the decoder is a [`SeamlessM4TDecoder`]. + """ +) +class SeamlessM4TTextToUnitModel(SeamlessM4TPreTrainedModel): + def __init__( + self, + config: SeamlessM4TConfig, + embed_tokens_decoder: nn.Embedding | None = None, + ): + r""" + embed_tokens_decoder (`nn.Embedding`, *optional*): + input embedding of the decoder. + """ + super().__init__(config) + + self.encoder = SeamlessM4TEncoder(config, is_t2u_encoder=True) + self.decoder = SeamlessM4TDecoder(config, embed_tokens_decoder) + + # Initialize weights and apply final processing + self.post_init() + + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.Tensor | None = None, + decoder_input_ids: torch.LongTensor | None = None, + decoder_attention_mask: torch.LongTensor | None = None, + encoder_outputs: tuple[tuple[torch.FloatTensor]] | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.FloatTensor | None = None, + decoder_inputs_embeds: torch.FloatTensor | None = None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + cache_position: torch.Tensor | None = None, + **kwargs, + ) -> tuple[torch.Tensor] | Seq2SeqModelOutput: + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + use_cache = use_cache if use_cache is not None else self.config.use_cache + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + if encoder_outputs is None: + encoder_outputs = self.encoder( + input_ids=input_ids, + attention_mask=attention_mask, + inputs_embeds=inputs_embeds, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + # If the user passed a tuple for encoder_outputs, we wrap it in a BaseModelOutput when return_dict=True + elif return_dict and not isinstance(encoder_outputs, BaseModelOutput): + encoder_outputs = BaseModelOutput( + last_hidden_state=encoder_outputs[0], + hidden_states=encoder_outputs[1] if len(encoder_outputs) > 1 else None, + attentions=encoder_outputs[2] if len(encoder_outputs) > 2 else None, + ) + + # decoder outputs consists of (dec_features, past_key_values, dec_hidden, dec_attn) + decoder_outputs = self.decoder( + input_ids=decoder_input_ids, + attention_mask=decoder_attention_mask, + encoder_hidden_states=encoder_outputs[0], + encoder_attention_mask=attention_mask, + past_key_values=past_key_values, + inputs_embeds=decoder_inputs_embeds, + use_cache=use_cache, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + cache_position=cache_position, + ) + + if not return_dict: + return decoder_outputs + encoder_outputs + + return Seq2SeqModelOutput( + last_hidden_state=decoder_outputs.last_hidden_state, + past_key_values=decoder_outputs.past_key_values, + decoder_hidden_states=decoder_outputs.hidden_states, + decoder_attentions=decoder_outputs.attentions, + cross_attentions=decoder_outputs.cross_attentions, + encoder_last_hidden_state=encoder_outputs.last_hidden_state, + encoder_hidden_states=encoder_outputs.hidden_states, + encoder_attentions=encoder_outputs.attentions, + ) + + +@auto_docstring( + custom_intro=""" + Transformer text-to-unit encoder-decoder with a language model head. The base encoder-decoder model is a [`SeamlessM4TTextToUnit`]. + """ +) +class SeamlessM4TTextToUnitForConditionalGeneration(SeamlessM4TPreTrainedModel, GenerationMixin): + _keys_to_ignore_on_load_missing = [ + "vocoder", + "speech_encoder", + "text_encoder", + "text_decoder", + ] + _tied_weights_keys = {"lm_head.weight": "model.decoder.embed_tokens.weight"} + + def __init__( + self, + config: SeamlessM4TConfig, + embed_tokens_decoder: nn.Embedding | None = None, + ): + r""" + embed_tokens_decoder (`nn.Embedding`, *optional*): + input embedding of the decoder. + """ + # update config - used principality for bos_token_id etc. + config = copy.deepcopy(config) + for param, val in config.to_dict().items(): + if param.startswith("t2u_"): + config.__setattr__(param[4:], val) + super().__init__(config) + + self.model = SeamlessM4TTextToUnitModel(config, embed_tokens_decoder) + + self.lm_head = nn.Linear(config.hidden_size, config.t2u_vocab_size, bias=False) + + # Initialize weights and apply final processing + self.post_init() + + def get_encoder(self): + return self.model.encoder + + def get_decoder(self): + return self.model.decoder + + def get_input_embeddings(self): + return self.model.decoder.embed_tokens + + def set_input_embeddings(self, value): + self.model.decoder.embed_tokens = value + + @auto_docstring(custom_args=SEAMLESS_M4T_COMMON_CUSTOM_ARGS) + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.Tensor | None = None, + decoder_input_ids: torch.LongTensor | None = None, + decoder_attention_mask: torch.LongTensor | None = None, + encoder_outputs: tuple[tuple[torch.FloatTensor]] | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.FloatTensor | None = None, + decoder_inputs_embeds: torch.FloatTensor | None = None, + labels: torch.LongTensor | None = None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + cache_position: torch.Tensor | None = None, + **kwargs, + ) -> Seq2SeqLMOutput | tuple[torch.FloatTensor]: + r""" + labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Labels for computing the masked language modeling loss. Indices should be in `[-100, 0, ..., + config.vocab_size]` (see `input_ids` docstring) Tokens with indices set to `-100` are ignored (masked), the + loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]` + """ + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + if labels is not None: + if use_cache: + logger.warning("The `use_cache` argument is changed to `False` since `labels` is provided.") + use_cache = False + if decoder_input_ids is None and decoder_inputs_embeds is None: + decoder_input_ids = shift_tokens_right( + labels, self.config.t2u_pad_token_id, self.config.t2u_decoder_start_token_id + ) + + outputs = self.model( + input_ids, + attention_mask=attention_mask, + decoder_input_ids=decoder_input_ids, + encoder_outputs=encoder_outputs, + decoder_attention_mask=decoder_attention_mask, + past_key_values=past_key_values, + inputs_embeds=inputs_embeds, + decoder_inputs_embeds=decoder_inputs_embeds, + use_cache=use_cache, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + cache_position=cache_position, + ) + lm_logits = self.lm_head(outputs[0]) + + masked_lm_loss = None + if labels is not None: + loss_fct = CrossEntropyLoss() + labels = labels.to(lm_logits.device) + masked_lm_loss = loss_fct(lm_logits.view(-1, self.config.vocab_size), labels.view(-1)) + + if not return_dict: + output = (lm_logits,) + outputs[1:] + return ((masked_lm_loss,) + output) if masked_lm_loss is not None else output + + return Seq2SeqLMOutput( + loss=masked_lm_loss, + logits=lm_logits, + past_key_values=outputs.past_key_values, + decoder_hidden_states=outputs.decoder_hidden_states, + decoder_attentions=outputs.decoder_attentions, + cross_attentions=outputs.cross_attentions, + encoder_last_hidden_state=outputs.encoder_last_hidden_state, + encoder_hidden_states=outputs.encoder_hidden_states, + encoder_attentions=outputs.encoder_attentions, + ) + + def prepare_decoder_input_ids_from_labels(self, labels: torch.Tensor): + return shift_tokens_right(labels, self.config.t2u_pad_token_id, self.config.t2u_decoder_start_token_id) + + +############ VOCODER related code ################ + + +# Copied from transformers.models.speecht5.modeling_speecht5.HifiGanResidualBlock +class HifiGanResidualBlock(nn.Module): + def __init__(self, channels, kernel_size=3, dilation=(1, 3, 5), leaky_relu_slope=0.1): + super().__init__() + self.leaky_relu_slope = leaky_relu_slope + + self.convs1 = nn.ModuleList( + [ + nn.Conv1d( + channels, + channels, + kernel_size, + stride=1, + dilation=dilation[i], + padding=self.get_padding(kernel_size, dilation[i]), + ) + for i in range(len(dilation)) + ] + ) + self.convs2 = nn.ModuleList( + [ + nn.Conv1d( + channels, + channels, + kernel_size, + stride=1, + dilation=1, + padding=self.get_padding(kernel_size, 1), + ) + for _ in range(len(dilation)) + ] + ) + + def get_padding(self, kernel_size, dilation=1): + return (kernel_size * dilation - dilation) // 2 + + def apply_weight_norm(self): + weight_norm = nn.utils.weight_norm + if hasattr(nn.utils.parametrizations, "weight_norm"): + weight_norm = nn.utils.parametrizations.weight_norm + + for layer in self.convs1: + weight_norm(layer) + for layer in self.convs2: + weight_norm(layer) + + def remove_weight_norm(self): + for layer in self.convs1: + nn.utils.remove_weight_norm(layer) + for layer in self.convs2: + nn.utils.remove_weight_norm(layer) + + def forward(self, hidden_states): + for conv1, conv2 in zip(self.convs1, self.convs2): + residual = hidden_states + hidden_states = nn.functional.leaky_relu(hidden_states, self.leaky_relu_slope) + hidden_states = conv1(hidden_states) + hidden_states = nn.functional.leaky_relu(hidden_states, self.leaky_relu_slope) + hidden_states = conv2(hidden_states) + hidden_states = hidden_states + residual + return hidden_states + + +class SeamlessM4TVariancePredictor(nn.Module): + def __init__(self, config): + super().__init__() + + embed_dim = config.unit_embed_dim + kernel_size = config.variance_predictor_kernel_size + var_pred_dropout = config.var_pred_dropout + + self.conv1 = nn.Conv1d( + embed_dim, + embed_dim, + kernel_size=kernel_size, + padding=(kernel_size - 1) // 2, + ) + self.activation_function = nn.ReLU() + self.ln1 = nn.LayerNorm(embed_dim) + self.dropout_module = nn.Dropout(p=var_pred_dropout) + self.conv2 = nn.Conv1d( + embed_dim, + embed_dim, + kernel_size=kernel_size, + padding=1, + ) + self.ln2 = nn.LayerNorm(embed_dim) + self.proj = nn.Linear(embed_dim, 1) + + def forward(self, hidden_states: Tensor) -> Tensor: + # Input: B x T x C; Output: B x T + hidden_states = self.conv1(hidden_states.transpose(1, 2)) + hidden_states = self.activation_function(hidden_states).transpose(1, 2) + hidden_states = self.dropout_module(self.ln1(hidden_states)) + hidden_states = self.conv2(hidden_states.transpose(1, 2)) + hidden_states = self.activation_function(hidden_states).transpose(1, 2) + hidden_states = self.dropout_module(self.ln2(hidden_states)) + return self.proj(hidden_states).squeeze(dim=2) + + +class SeamlessM4THifiGan(nn.Module): + def __init__(self, config: SeamlessM4TConfig): + super().__init__() + model_in_dim = config.unit_embed_dim + config.lang_embed_dim + config.spkr_embed_dim + self.leaky_relu_slope = config.leaky_relu_slope + self.num_kernels = len(config.resblock_kernel_sizes) + self.num_upsamples = len(config.upsample_rates) + self.conv_pre = nn.Conv1d( + model_in_dim, + config.upsample_initial_channel, + kernel_size=7, + stride=1, + padding=3, + ) + + self.upsampler = nn.ModuleList() + for i, (upsample_rate, kernel_size) in enumerate(zip(config.upsample_rates, config.upsample_kernel_sizes)): + self.upsampler.append( + nn.ConvTranspose1d( + config.upsample_initial_channel // (2**i), + config.upsample_initial_channel // (2 ** (i + 1)), + kernel_size=kernel_size, + stride=upsample_rate, + padding=(kernel_size - upsample_rate) // 2, + ) + ) + + self.resblocks = nn.ModuleList() + for i in range(len(self.upsampler)): + channels = config.upsample_initial_channel // (2 ** (i + 1)) + for kernel_size, dilation in zip(config.resblock_kernel_sizes, config.resblock_dilation_sizes): + self.resblocks.append(HifiGanResidualBlock(channels, kernel_size, dilation, config.leaky_relu_slope)) + + self.conv_post = nn.Conv1d(channels, 1, kernel_size=7, stride=1, padding=3) + + @deprecate_kwarg("input_embeds", version="5.6.0", new_name="inputs_embeds") + def forward(self, inputs_embeds: torch.FloatTensor) -> torch.FloatTensor: + r""" + Converts a log-mel spectrogram into a speech waveform. Passing a batch of log-mel spectrograms returns a batch + of speech waveforms. Passing a single, un-batched log-mel spectrogram returns a single, un-batched speech + waveform. + + Args: + spectrogram (`torch.FloatTensor`): + Tensor containing the log-mel spectrograms. Can be batched and of shape `(batch_size, sequence_length, + model_in_dim)`, or un-batched and of shape `(sequence_length, model_in_dim)`. Note that `model_in_dim` + is the sum of `config.unit_embed_dim`, `config.lang_embed_dim` and `config.spkr_embed_dim`. + + Returns: + `torch.FloatTensor`: Tensor containing the speech waveform. If the input spectrogram is batched, will be of + shape `(batch_size, num_frames,)`. If un-batched, will be of shape `(num_frames,)`. + """ + + hidden_states = self.conv_pre(inputs_embeds) + for i in range(self.num_upsamples): + hidden_states = nn.functional.leaky_relu(hidden_states, self.leaky_relu_slope) + hidden_states = self.upsampler[i](hidden_states) + + res_state = self.resblocks[i * self.num_kernels](hidden_states) + for j in range(1, self.num_kernels): + res_state += self.resblocks[i * self.num_kernels + j](hidden_states) + hidden_states = res_state / self.num_kernels + + hidden_states = nn.functional.leaky_relu(hidden_states) + hidden_states = self.conv_post(hidden_states) + hidden_states = torch.tanh(hidden_states) + + # remove seq-len dim since this collapses to 1 + waveform = hidden_states.squeeze(1) + + return waveform + + +@auto_docstring( + custom_intro=""" + Code HiFi-GAN vocoder as described in this [repository](https://github.com/facebookresearch/speech-resynthesis). + """ +) +class SeamlessM4TCodeHifiGan(PreTrainedModel): + config: SeamlessM4TConfig + main_input_name = "inputs_embeds" + input_modalities = "audio" + _no_split_modules = [] + + def __init__(self, config): + super().__init__(config) + + self.pad_token_id = config.t2u_pad_token_id + self.dur_predictor = SeamlessM4TVariancePredictor(config) + + self.unit_embedding = nn.Embedding(config.unit_hifi_gan_vocab_size, config.unit_embed_dim) + self.speaker_embedding = nn.Embedding(config.vocoder_num_spkrs, config.spkr_embed_dim) + self.language_embedding = nn.Embedding(config.vocoder_num_langs, config.lang_embed_dim) + + self.hifi_gan = SeamlessM4THifiGan(config) + + # Initialize weights and apply final processing + self.post_init() + + def _get_dur_output_lengths(self, input_ids, dur_out): + """ + Computes the output length after the duration layer. + """ + unit_lengths = (input_ids != self.pad_token_id).sum(1) + + # take care of edge cases where no padding or too many padding + unit_lengths = torch.clamp(unit_lengths, 0, dur_out.shape[1] - 1) + + cumulative_dur_out = torch.cumsum(dur_out, dim=1) + unit_lengths = cumulative_dur_out.gather(dim=1, index=unit_lengths.unsqueeze(1)).squeeze() + + return unit_lengths + + def _get_output_hifigan_lengths(self, input_lengths: torch.LongTensor | int): + """ + Computes the output length of the hifigan convolutional layers + """ + + def _conv_out_length(input_length, kernel_size, stride, pad, dilation=1): + # 1D convolutional layer output length formula taken + # from https://pytorch.org/docs/stable/generated/torch.nn.Conv1d.html + return ( + torch.div(input_length + 2 * pad - dilation * (kernel_size - 1) - 1, stride, rounding_mode="floor") + 1 + ) + + def _transpose_conv_out_length(input_length, kernel_size, stride, pad, dilation=1): + return (input_length - 1) * stride - 2 * pad + dilation * (kernel_size - 1) + 1 + + # conv_pre + input_lengths = _conv_out_length(input_lengths, 7, 1, 3) + + # upsampler + for i, (upsample_rate, kernel_size) in enumerate( + zip(self.config.upsample_rates, self.config.upsample_kernel_sizes) + ): + input_lengths = _transpose_conv_out_length( + input_lengths, kernel_size, upsample_rate, (kernel_size - upsample_rate) // 2 + ) + + # resblock + for i in range(len(self.config.upsample_rates)): + for kernel_size, dilation in zip(self.config.resblock_kernel_sizes, self.config.resblock_dilation_sizes): + for dil in dilation: + input_lengths = _conv_out_length( + input_lengths, kernel_size, 1, (kernel_size - 1) * dil // 2, dilation=dil + ) + + for dil in dilation: + input_lengths = _conv_out_length(input_lengths, kernel_size, 1, (kernel_size - 1) // 2, dilation=1) + + # conv_post + input_lengths = _conv_out_length(input_lengths, 7, 1, 3) + + return input_lengths + + def forward( + self, input_ids: torch.LongTensor, spkr_id: torch.Tensor, lang_id: torch.Tensor, **kwargs + ) -> tuple[torch.Tensor]: + """ + Args: + input_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`): + Indices of input sequence tokens in the vocabulary. + + Indices can be obtained using [`SeamlessM4TTextToUnitForConditionalGeneration`]. [What are input + IDs?](../glossary#input-ids) + spkr_id (`int`, *optional*): + The id of the speaker used for speech synthesis. Must be lower than `config.vocoder_num_spkrs`. + tgt_lang (`str`, *optional*): + The language id to use as target language for translation. + """ + hidden_states = self.unit_embedding(input_ids).transpose(1, 2) + spkr = self.speaker_embedding(spkr_id).transpose(1, 2) + lang = self.language_embedding(lang_id).transpose(1, 2) + + log_dur_pred = self.dur_predictor(hidden_states.transpose(1, 2)) + dur_out = torch.clamp(torch.round(torch.expm1(log_dur_pred)).long(), min=1) + # B x C x T + if hidden_states.size(0) == 1: + hidden_states = torch.repeat_interleave(hidden_states, dur_out.view(-1), dim=2) + else: + # if batched sample, need to interleave per sample, and pad -> loss of parallelism + if hidden_states.shape[0] > 1 and self.training: + logger.warning( + """`self.training=True` and you use batching. You lose parallelism during the hifigan + forward pass because the samples are interleaved.""" + ) + hidden_states = [ + torch.repeat_interleave(hidden_state, duration, dim=-1).transpose(0, 1) + for (hidden_state, duration) in zip(hidden_states, dur_out) + ] + + hidden_states = nn.utils.rnn.pad_sequence(hidden_states, batch_first=True).transpose(1, 2) + + spkr = spkr.repeat(1, 1, hidden_states.shape[-1]) + lang = lang.repeat(1, 1, hidden_states.shape[-1]) + hidden_states = torch.cat([lang, hidden_states, spkr], dim=1) + + hidden_states = self.hifi_gan(hidden_states) + + unit_lengths = self._get_dur_output_lengths(input_ids, dur_out) + lengths = self._get_output_hifigan_lengths(unit_lengths) + + return hidden_states, lengths + + def apply_weight_norm(self): + weight_norm = nn.utils.weight_norm + if hasattr(nn.utils.parametrizations, "weight_norm"): + weight_norm = nn.utils.parametrizations.weight_norm + + weight_norm(self.hifi_gan.conv_pre) + for layer in self.hifi_gan.upsampler: + weight_norm(layer) + for layer in self.hifi_gan.resblocks: + layer.apply_weight_norm() + weight_norm(self.hifi_gan.conv_post) + + def remove_weight_norm(self): + nn.utils.remove_weight_norm(self.hifi_gan.conv_pre) + for layer in self.hifi_gan.upsampler: + nn.utils.remove_weight_norm(layer) + for layer in self.hifi_gan.resblocks: + layer.remove_weight_norm() + nn.utils.remove_weight_norm(self.hifi_gan.conv_post) + + +############ WHOLE MODEL related code ################ + + +@auto_docstring( + custom_intro=""" + The text-to-text SeamlessM4T Model transformer which can be used for T2TT. + """ +) +class SeamlessM4TForTextToText(SeamlessM4TPreTrainedModel, GenerationMixin): + _keys_to_ignore_on_load_missing = ["speech_encoder", "t2u_model", "vocoder"] + main_input_name = "input_ids" + + _tied_weights_keys = { + "lm_head.weight": "shared.weight", + "text_encoder.embed_tokens.weight": "shared.weight", + "text_decoder.embed_tokens.weight": "shared.weight", + } + + def __init__(self, config: SeamlessM4TConfig): + super().__init__(config) + + self.shared = nn.Embedding(config.vocab_size, config.hidden_size, config.pad_token_id) + + self.text_encoder = SeamlessM4TEncoder(config) + self.text_decoder = SeamlessM4TDecoder(config) + self.lm_head = nn.Linear(config.hidden_size, config.vocab_size, bias=False) + + # Initialize weights and apply final processing + self.post_init() + + def get_encoder(self): + return self.text_encoder + + def get_decoder(self): + return self.text_decoder + + def get_input_embeddings(self): + return self.text_decoder.embed_tokens + + def set_input_embeddings(self, value): + self.text_encoder.embed_tokens = value + self.text_decoder.embed_tokens = value + self.shared = value + + @auto_docstring(custom_args=SEAMLESS_M4T_COMMON_CUSTOM_ARGS) + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.Tensor | None = None, + decoder_input_ids: torch.LongTensor | None = None, + decoder_attention_mask: torch.LongTensor | None = None, + encoder_outputs: tuple[tuple[torch.FloatTensor]] | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.FloatTensor | None = None, + decoder_inputs_embeds: torch.FloatTensor | None = None, + labels: torch.LongTensor | None = None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + **kwargs, + ) -> Seq2SeqLMOutput | tuple[torch.FloatTensor]: + r""" + labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Labels for computing the masked language modeling loss. Indices should be in `[-100, 0, ..., + config.vocab_size]` (see `input_ids` docstring) Tokens with indices set to `-100` are ignored (masked), the + loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]` + """ + if labels is not None: + if use_cache: + logger.warning("The `use_cache` argument is changed to `False` since `labels` is provided.") + use_cache = False + if decoder_input_ids is None and decoder_inputs_embeds is None: + decoder_input_ids = shift_tokens_right( + labels, self.config.pad_token_id, self.config.decoder_start_token_id + ) + + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + use_cache = use_cache if use_cache is not None else self.config.use_cache + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + if encoder_outputs is None: + encoder_outputs = self.text_encoder( + input_ids=input_ids, + attention_mask=attention_mask, + inputs_embeds=inputs_embeds, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + # If the user passed a tuple for encoder_outputs, we wrap it in a BaseModelOutput when return_dict=True + elif return_dict and not isinstance(encoder_outputs, BaseModelOutput): + encoder_outputs = BaseModelOutput( + last_hidden_state=encoder_outputs[0], + hidden_states=encoder_outputs[1] if len(encoder_outputs) > 1 else None, + attentions=encoder_outputs[2] if len(encoder_outputs) > 2 else None, + ) + + encoder_attention_mask = attention_mask + + # decoder outputs consists of (dec_features, past_key_values, dec_hidden, dec_attn) + decoder_outputs = self.text_decoder( + input_ids=decoder_input_ids, + attention_mask=decoder_attention_mask, + encoder_hidden_states=encoder_outputs[0], + encoder_attention_mask=encoder_attention_mask, + past_key_values=past_key_values, + inputs_embeds=decoder_inputs_embeds, + use_cache=use_cache, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + + lm_logits = self.lm_head(decoder_outputs[0]) + + masked_lm_loss = None + if labels is not None: + loss_fct = CrossEntropyLoss() + labels = labels.to(lm_logits.device) + masked_lm_loss = loss_fct(lm_logits.view(-1, self.config.vocab_size), labels.view(-1)) + + if not return_dict: + outputs = decoder_outputs + encoder_outputs + output = (lm_logits,) + outputs[1:] + return ((masked_lm_loss,) + output) if masked_lm_loss is not None else output + + return Seq2SeqLMOutput( + loss=masked_lm_loss, + logits=lm_logits, + past_key_values=decoder_outputs.past_key_values, + decoder_hidden_states=decoder_outputs.hidden_states, + decoder_attentions=decoder_outputs.attentions, + cross_attentions=decoder_outputs.cross_attentions, + encoder_last_hidden_state=encoder_outputs.last_hidden_state, + encoder_hidden_states=encoder_outputs.hidden_states, + encoder_attentions=encoder_outputs.attentions, + ) + + def generate( + self, + input_ids=None, + tgt_lang=None, + generation_config=None, + logits_processor=None, + stopping_criteria=None, + prefix_allowed_tokens_fn=None, + synced_gpus=False, + **kwargs, + ): + """ + Generates sequences of token ids. + + + + Most generation-controlling parameters are set in `generation_config` which, if not passed, will be set to the + model's default generation configuration. You can override any `generation_config` by passing the corresponding + parameters to generate(), e.g. `.generate(inputs, num_beams=4, do_sample=True)`. + + For an overview of generation strategies and code examples, check out the [following + guide](./generation_strategies). + + + + Parameters: + input_ids (`torch.Tensor` of varying shape depending on the modality, *optional*): + Indices of input sequence tokens in the vocabulary. + + Indices can be obtained using [`SeamlessM4TTokenizer`] or [`SeamlessM4TProcessor`]. See + [`PreTrainedTokenizer.encode`] and [`PreTrainedTokenizer.__call__`] for details. + + [What are input IDs?](../glossary#input-ids) + tgt_lang (`str`, *optional*): + The language to use as target language for translation. + generation_config (`~generation.GenerationConfig`, *optional*): + The generation configuration to be used as base parametrization for the generation call. `**kwargs` + passed to generate matching the attributes of `generation_config` will override them. If + `generation_config` is not provided, the default will be used, which had the following loading + priority: 1) from the `generation_config.json` model file, if it exists; 2) from the model + configuration. Please note that unspecified parameters will inherit [`~generation.GenerationConfig`]'s + default values, whose documentation should be checked to parameterize generation. + logits_processor (`LogitsProcessorList`, *optional*): + Custom logits processors that complement the default logits processors built from arguments and + generation config. If a logit processor is passed that is already created with the arguments or a + generation config an error is thrown. This feature is intended for advanced users. + stopping_criteria (`StoppingCriteriaList`, *optional*): + Custom stopping criteria that complement the default stopping criteria built from arguments and a + generation config. If a stopping criteria is passed that is already created with the arguments or a + generation config an error is thrown. This feature is intended for advanced users. + prefix_allowed_tokens_fn (`Callable[[int, torch.Tensor], list[int]]`, *optional*): + If provided, this function constraints the beam search to allowed tokens only at each step. If not + provided no constraint is applied. This function takes 2 arguments: the batch ID `batch_id` and + `input_ids`. It has to return a list with the allowed tokens for the next generation step conditioned + on the batch ID `batch_id` and the previously generated tokens `inputs_ids`. This argument is useful + for constrained generation conditioned on the prefix, as described in [Autoregressive Entity + Retrieval](https://huggingface.co/papers/2010.00904). + synced_gpus (`bool`, *optional*, defaults to `False`): + Whether to continue running the while loop until max_length (needed to avoid deadlocking with + `FullyShardedDataParallel` and DeepSpeed ZeRO Stage 3). + kwargs (`dict[str, Any]`, *optional*): + Ad hoc parametrization of `generate_config` and/or additional model-specific kwargs that will be + forwarded to the `forward` function of the model. + + Return: + [`~utils.ModelOutput`] or `torch.LongTensor`: A [`~utils.ModelOutput`] (if `return_dict_in_generate=True` + or when `config.return_dict_in_generate=True`) or a `torch.FloatTensor`. The possible + [`~utils.ModelOutput`] types are: + - [`~generation.GenerateEncoderDecoderOutput`], + - [`~generation.GenerateBeamEncoderDecoderOutput`] + """ + # prepare text_decoder_input_ids + text_decoder_input_ids = kwargs.pop("decoder_input_ids", None) + # overwrite text_decoder_input_ids if tgt_lang is passed. The latter gets priority over decoder_input_ids. + if tgt_lang is not None: + batch_size = len(input_ids) if input_ids is not None else len(kwargs.get("inputs_embeds")) + + if hasattr(self.generation_config, "text_decoder_lang_to_code_id"): + # also accept __xxx__ + tgt_lang = tgt_lang.replace("__", "") + if tgt_lang not in self.generation_config.text_decoder_lang_to_code_id: + raise ValueError( + f"""`tgt_lang={tgt_lang}` is not supported by this model. Please specify a `tgt_lang` in + {", ".join(self.generation_config.text_decoder_lang_to_code_id.keys())}""" + ) + # tgt_lang gets priority over decoder input ids + text_tgt_lang_id = self.generation_config.text_decoder_lang_to_code_id.get(tgt_lang) + text_decoder_input_ids = torch.tensor([[text_tgt_lang_id]] * batch_size, device=self.device) + else: + raise ValueError( + """This model generation config doesn't have a `text_decoder_lang_to_code_id` key which maps + the target language to the right token id. Make sure to load the right generation config.""" + ) + else: + # only a warning, otherwise errors appear in the tests + logger.warning( + """You must either specify a `tgt_lang` or pass a correct `text_decoder_input_ids` to get + a correct generation, otherwise the generation will probably make no sense.""" + ) + + return super().generate( + input_ids, + generation_config, + logits_processor, + stopping_criteria, + prefix_allowed_tokens_fn, + synced_gpus, + decoder_input_ids=text_decoder_input_ids, + **kwargs, + ) + + +@auto_docstring( + custom_intro=""" + The speech-to-text SeamlessM4T Model transformer which can be used for S2TT. + """ +) +class SeamlessM4TForSpeechToText(SeamlessM4TPreTrainedModel, GenerationMixin): + input_modalities = "audio" + _keys_to_ignore_on_load_missing = ["text_encoder", "t2u_model", "vocoder"] + main_input_name = "input_features" + + _tied_weights_keys = { + "lm_head.weight": "shared.weight", + "text_decoder.embed_tokens.weight": "shared.weight", + } + + def __init__(self, config: SeamlessM4TConfig): + super().__init__(config) + + self.shared = nn.Embedding(config.vocab_size, config.hidden_size, config.pad_token_id) + self.speech_encoder = SeamlessM4TSpeechEncoder(config) + self.text_decoder = SeamlessM4TDecoder(config) + self.lm_head = nn.Linear(config.hidden_size, config.vocab_size, bias=False) + + # Initialize weights and apply final processing + self.post_init() + + def get_encoder(self): + return self.speech_encoder + + def get_decoder(self): + return self.text_decoder + + def get_input_embeddings(self): + return self.text_decoder.embed_tokens + + def set_input_embeddings(self, value): + self.text_decoder.embed_tokens = value + + @auto_docstring(custom_args=SEAMLESS_M4T_COMMON_CUSTOM_ARGS) + def forward( + self, + input_features: torch.LongTensor | None = None, + attention_mask: torch.Tensor | None = None, + decoder_input_ids: torch.LongTensor | None = None, + decoder_attention_mask: torch.LongTensor | None = None, + encoder_outputs: tuple[tuple[torch.FloatTensor]] | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.FloatTensor | None = None, + decoder_inputs_embeds: torch.FloatTensor | None = None, + labels: torch.LongTensor | None = None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + **kwargs, + ) -> Seq2SeqLMOutput | tuple[torch.FloatTensor]: + r""" + labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Labels for computing the masked language modeling loss. Indices should be in `[-100, 0, ..., + config.vocab_size]` (see `input_ids` docstring) Tokens with indices set to `-100` are ignored (masked), the + loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]` + """ + if labels is not None: + if use_cache: + logger.warning("The `use_cache` argument is changed to `False` since `labels` is provided.") + use_cache = False + if decoder_input_ids is None and decoder_inputs_embeds is None: + decoder_input_ids = shift_tokens_right( + labels, self.config.pad_token_id, self.config.decoder_start_token_id + ) + + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + use_cache = use_cache if use_cache is not None else self.config.use_cache + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + if encoder_outputs is None: + encoder_outputs = self.speech_encoder( + input_features=input_features, + attention_mask=attention_mask, + inputs_embeds=inputs_embeds, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + # If the user passed a tuple for encoder_outputs, we wrap it in a BaseModelOutput when return_dict=True + elif return_dict and not isinstance(encoder_outputs, BaseModelOutput): + encoder_outputs = BaseModelOutput( + last_hidden_state=encoder_outputs[0], + hidden_states=encoder_outputs[1] if len(encoder_outputs) > 1 else None, + attentions=encoder_outputs[2] if len(encoder_outputs) > 2 else None, + ) + + encoder_attention_mask = attention_mask + if attention_mask is not None: + sub_sampled_lengths = self._compute_sub_sample_lengths_from_attention_mask(attention_mask).to( + encoder_outputs[0].device + ) + encoder_attention_mask = _compute_new_attention_mask( + hidden_states=encoder_outputs[0], seq_lens=sub_sampled_lengths + ) + + # decoder outputs consists of (dec_features, past_key_values, dec_hidden, dec_attn) + decoder_outputs = self.text_decoder( + input_ids=decoder_input_ids, + attention_mask=decoder_attention_mask, + encoder_hidden_states=encoder_outputs[0], + encoder_attention_mask=encoder_attention_mask, + past_key_values=past_key_values, + inputs_embeds=decoder_inputs_embeds, + use_cache=use_cache, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + + lm_logits = self.lm_head(decoder_outputs[0]) + + masked_lm_loss = None + if labels is not None: + loss_fct = CrossEntropyLoss() + labels = labels.to(lm_logits.device) + masked_lm_loss = loss_fct(lm_logits.view(-1, self.config.vocab_size), labels.view(-1)) + + if not return_dict: + outputs = decoder_outputs + encoder_outputs + output = (lm_logits,) + outputs[1:] + return ((masked_lm_loss,) + output) if masked_lm_loss is not None else output + + return Seq2SeqLMOutput( + loss=masked_lm_loss, + logits=lm_logits, + past_key_values=decoder_outputs.past_key_values, + decoder_hidden_states=decoder_outputs.hidden_states, + decoder_attentions=decoder_outputs.attentions, + cross_attentions=decoder_outputs.cross_attentions, + encoder_last_hidden_state=encoder_outputs.last_hidden_state, + encoder_hidden_states=encoder_outputs.hidden_states, + encoder_attentions=encoder_outputs.attentions, + ) + + def generate( + self, + input_features=None, + tgt_lang=None, + generation_config=None, + logits_processor=None, + stopping_criteria=None, + prefix_allowed_tokens_fn=None, + synced_gpus=False, + **kwargs, + ): + """ + Generates sequences of token ids. + + + + Most generation-controlling parameters are set in `generation_config` which, if not passed, will be set to the + model's default generation configuration. You can override any `generation_config` by passing the corresponding + parameters to generate(), e.g. `.generate(inputs, num_beams=4, do_sample=True)`. + + For an overview of generation strategies and code examples, check out the [following + guide](./generation_strategies). + + + + Parameters: + input_features (`torch.FloatTensor` of shape `(batch_size, sequence_length, num_banks)`): + Input audio features. This should be returned by the [`SeamlessM4TFeatureExtractor`] class or the + [`SeamlessM4TProcessor`] class. See [`SeamlessM4TFeatureExtractor.__call__`] for details. + + tgt_lang (`str`, *optional*): + The language to use as target language for translation. + generation_config (`~generation.GenerationConfig`, *optional*): + The generation configuration to be used as base parametrization for the generation call. `**kwargs` + passed to generate matching the attributes of `generation_config` will override them. If + `generation_config` is not provided, the default will be used, which had the following loading + priority: 1) from the `generation_config.json` model file, if it exists; 2) from the model + configuration. Please note that unspecified parameters will inherit [`~generation.GenerationConfig`]'s + default values, whose documentation should be checked to parameterize generation. + logits_processor (`LogitsProcessorList`, *optional*): + Custom logits processors that complement the default logits processors built from arguments and + generation config. If a logit processor is passed that is already created with the arguments or a + generation config an error is thrown. This feature is intended for advanced users. + stopping_criteria (`StoppingCriteriaList`, *optional*): + Custom stopping criteria that complement the default stopping criteria built from arguments and a + generation config. If a stopping criteria is passed that is already created with the arguments or a + generation config an error is thrown. This feature is intended for advanced users. + prefix_allowed_tokens_fn (`Callable[[int, torch.Tensor], list[int]]`, *optional*): + If provided, this function constraints the beam search to allowed tokens only at each step. If not + provided no constraint is applied. This function takes 2 arguments: the batch ID `batch_id` and + `input_ids`. It has to return a list with the allowed tokens for the next generation step conditioned + on the batch ID `batch_id` and the previously generated tokens `inputs_ids`. This argument is useful + for constrained generation conditioned on the prefix, as described in [Autoregressive Entity + Retrieval](https://huggingface.co/papers/2010.00904). + synced_gpus (`bool`, *optional*, defaults to `False`): + Whether to continue running the while loop until max_length (needed to avoid deadlocking with + `FullyShardedDataParallel` and DeepSpeed ZeRO Stage 3). + kwargs (`dict[str, Any]`, *optional*): + Ad hoc parametrization of `generate_config` and/or additional model-specific kwargs that will be + forwarded to the `forward` function of the model. + + Return: + [`~utils.ModelOutput`] or `torch.LongTensor`: A [`~utils.ModelOutput`] (if `return_dict_in_generate=True` + or when `config.return_dict_in_generate=True`) or a `torch.FloatTensor`. The possible + [`~utils.ModelOutput`] types are: + - [`~generation.GenerateEncoderDecoderOutput`], + - [`~generation.GenerateBeamEncoderDecoderOutput`] + """ + text_decoder_input_ids = kwargs.pop("decoder_input_ids", None) + # overwrite text_decoder_input_ids if tgt_lang is passed. The latter gets priority over decoder_input_ids. + input_features = input_features if input_features is not None else kwargs.pop("inputs") + if tgt_lang is not None: + inputs = kwargs.get("inputs_embeds") if input_features is None else input_features + inputs = ( + inputs + if inputs is not None + else kwargs.get("encoder_outputs", {"last_hidden_state": None})["last_hidden_state"] + ) + batch_size = len(inputs) + + if hasattr(self.generation_config, "text_decoder_lang_to_code_id"): + # also accept __xxx__ + tgt_lang = tgt_lang.replace("__", "") + if tgt_lang not in self.generation_config.text_decoder_lang_to_code_id: + raise ValueError( + f"""`tgt_lang={tgt_lang}` is not supported by this model. Please specify a `tgt_lang` in + {", ".join(self.generation_config.text_decoder_lang_to_code_id.keys())}""" + ) + # tgt_lang gets priority over decoder input ids + text_tgt_lang_id = self.generation_config.text_decoder_lang_to_code_id.get(tgt_lang) + text_decoder_input_ids = torch.tensor([[text_tgt_lang_id]] * batch_size, device=self.device) + else: + raise ValueError( + """This model generation config doesn't have a `text_decoder_lang_to_code_id` key which maps + the target language to the right token id. Make sure to load the right generation config.""" + ) + else: + # only a warning, otherwise errors appear in the tests + logger.warning( + """You must either specify a `tgt_lang` or pass a correct `text_decoder_input_ids` to get + a correct generation, otherwise the generation will probably make no sense.""" + ) + return super().generate( + input_features, + generation_config, + logits_processor, + stopping_criteria, + prefix_allowed_tokens_fn, + synced_gpus, + decoder_input_ids=text_decoder_input_ids, + **kwargs, + ) + + +@auto_docstring( + custom_intro=""" + The text-to-speech SeamlessM4T Model transformer which can be used for T2ST. + """ +) +class SeamlessM4TForTextToSpeech(SeamlessM4TPreTrainedModel, GenerationMixin): + output_modalities = ("audio",) + _keys_to_ignore_on_load_missing = ["speech_encoder"] + main_input_name = "input_ids" + + _tied_weights_keys = { + "lm_head.weight": "shared.weight", + "text_encoder.embed_tokens.weight": "shared.weight", + "text_decoder.embed_tokens.weight": "shared.weight", + } + + def __init__(self, config: SeamlessM4TConfig): + super().__init__(config) + + self.shared = nn.Embedding(config.vocab_size, config.hidden_size, config.pad_token_id) + + self.text_encoder = SeamlessM4TEncoder(config) + self.text_decoder = SeamlessM4TDecoder(config) + self.lm_head = nn.Linear(config.hidden_size, config.vocab_size, bias=False) + + self.t2u_model = SeamlessM4TTextToUnitForConditionalGeneration(config) + self.vocoder = SeamlessM4TCodeHifiGan(config) + + # Initialize weights and apply final processing + self.post_init() + + def get_encoder(self): + return self.text_encoder + + def get_decoder(self): + return self.text_decoder + + def get_input_embeddings(self): + return self.text_decoder.embed_tokens + + def set_input_embeddings(self, value): + self.text_encoder.embed_tokens = value + self.text_decoder.embed_tokens = value + self.shared = value + + @auto_docstring(custom_args=SEAMLESS_M4T_COMMON_CUSTOM_ARGS) + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.Tensor | None = None, + decoder_input_ids: torch.LongTensor | None = None, + decoder_attention_mask: torch.LongTensor | None = None, + encoder_outputs: tuple[tuple[torch.FloatTensor]] | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.FloatTensor | None = None, + decoder_inputs_embeds: torch.FloatTensor | None = None, + labels: torch.LongTensor | None = None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + cache_position: torch.Tensor | None = None, + **kwargs, + ) -> Seq2SeqLMOutput | tuple[torch.FloatTensor]: + r""" + labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Labels for computing the masked language modeling loss. Indices should be in `[-100, 0, ..., + config.vocab_size]` (see `input_ids` docstring) Tokens with indices set to `-100` are ignored (masked), the + loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]` + """ + if labels is not None: + if use_cache: + logger.warning("The `use_cache` argument is changed to `False` since `labels` is provided.") + use_cache = False + if decoder_input_ids is None and decoder_inputs_embeds is None: + decoder_input_ids = shift_tokens_right( + labels, self.config.pad_token_id, self.config.decoder_start_token_id + ) + + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + use_cache = use_cache if use_cache is not None else self.config.use_cache + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + if encoder_outputs is None: + # if encoder_outputs is not None, it's probably used within a .generate method so no need to warn + logger.warning( + "This is the same forward method as `SeamlessM4TForTextToText`." + "It doesn't use the text-to-unit model `SeamlessM4TTextToUnitForConditionalGeneration`." + "If you want to generate speech, use the `.generate` method." + ) + encoder_outputs = self.text_encoder( + input_ids=input_ids, + attention_mask=attention_mask, + inputs_embeds=inputs_embeds, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + # If the user passed a tuple for encoder_outputs, we wrap it in a BaseModelOutput when return_dict=True + elif return_dict and not isinstance(encoder_outputs, BaseModelOutput): + encoder_outputs = BaseModelOutput( + last_hidden_state=encoder_outputs[0], + hidden_states=encoder_outputs[1] if len(encoder_outputs) > 1 else None, + attentions=encoder_outputs[2] if len(encoder_outputs) > 2 else None, + ) + + encoder_attention_mask = attention_mask + + # decoder outputs consists of (dec_features, past_key_values, dec_hidden, dec_attn) + decoder_outputs = self.text_decoder( + input_ids=decoder_input_ids, + attention_mask=decoder_attention_mask, + encoder_hidden_states=encoder_outputs[0], + encoder_attention_mask=encoder_attention_mask, + past_key_values=past_key_values, + inputs_embeds=decoder_inputs_embeds, + use_cache=use_cache, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + cache_position=cache_position, + ) + + lm_logits = self.lm_head(decoder_outputs[0]) + + masked_lm_loss = None + if labels is not None: + loss_fct = CrossEntropyLoss() + labels = labels.to(lm_logits.device) + masked_lm_loss = loss_fct(lm_logits.view(-1, self.config.vocab_size), labels.view(-1)) + + if not return_dict: + outputs = decoder_outputs + encoder_outputs + output = (lm_logits,) + outputs[1:] + return ((masked_lm_loss,) + output) if masked_lm_loss is not None else output + + return Seq2SeqLMOutput( + loss=masked_lm_loss, + logits=lm_logits, + past_key_values=decoder_outputs.past_key_values, + decoder_hidden_states=decoder_outputs.hidden_states, + decoder_attentions=decoder_outputs.attentions, + cross_attentions=decoder_outputs.cross_attentions, + encoder_last_hidden_state=encoder_outputs.last_hidden_state, + encoder_hidden_states=encoder_outputs.hidden_states, + encoder_attentions=encoder_outputs.attentions, + ) + + @torch.no_grad() + def generate( + self, + input_ids: torch.Tensor | None = None, + return_intermediate_token_ids: bool | None = None, + tgt_lang: str | None = None, + spkr_id: int | None = 0, + **kwargs, + ) -> torch.Tensor | SeamlessM4TGenerationOutput: + """ + Generates translated audio waveforms. + + + + This method successively calls the `.generate` function of two different sub-models. You can specify keyword + arguments at two different levels: general arguments that will be passed to both models, or prefixed arguments + that will be passed to one of them. + + For example, calling `.generate(input_ids, num_beams=4, speech_do_sample=True)` will successively perform + beam-search decoding on the text model, and multinomial beam-search sampling on the speech model. + + For an overview of generation strategies and code examples, check out the [following + guide](./generation_strategies). + + + + Args: + input_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`): + Indices of input sequence tokens in the vocabulary. + + Indices can be obtained using [`SeamlessM4TTokenizer`] or [`SeamlessM4TProcessor`]. See + [`PreTrainedTokenizer.encode`] and [`PreTrainedTokenizer.__call__`] for details. + + [What are input IDs?](../glossary#input-ids) + return_intermediate_token_ids (`bool`, *optional*): + If `True`, also returns the intermediate generated text and unit tokens. Set to `True` if you also want + to get translated text alongside the audio. + tgt_lang (`str`, *optional*): + The language to use as target language for translation. + spkr_id (`int`, *optional*, defaults to 0): + The id of the speaker used for speech synthesis. Must be lower than `config.vocoder_num_spkrs`. + kwargs (*optional*): + Remaining dictionary of keyword arguments that will be passed to [`GenerationMixin.generate`]. Keyword + arguments are of two types: + + - Without a prefix, they will be entered as `**kwargs` for the `generate` method of each sub-model, + except for `decoder_input_ids` which will only be passed through the text components. + - With a *text_* or *speech_* prefix, they will be input for the `generate` method of the + text model and speech model respectively. It has the priority over the keywords without a prefix. + + This means you can, for example, specify a generation strategy for one generation but not for the + other. + + + Returns: + `Union[SeamlessM4TGenerationOutput, tuple[Tensor]]`: + - If `return_intermediate_token_ids`, returns [`SeamlessM4TGenerationOutput`]. + - If not `return_intermediate_token_ids`, returns a tuple composed of waveforms of shape `(batch_size, + sequence_length)` and `waveform_lengths` which gives the length of each sample. + """ + batch_size = len(input_ids) if input_ids is not None else len(kwargs.get("inputs_embeds")) + + if tgt_lang is None: + raise ValueError("You must specify a `tgt_lang` to generate translated speech.") + else: + # also accept __xxx__ + tgt_lang = tgt_lang.replace("__", "") + for key in ["text_decoder_lang_to_code_id", "t2u_lang_code_to_id", "vocoder_lang_code_to_id"]: + lang_code_to_id = getattr(self.generation_config, key, None) + if lang_code_to_id is None: + raise ValueError( + f"""This model generation config doesn't have a `{key}` key which maps the target language + to the right token id. Make sure to load the right generation config.""" + ) + elif tgt_lang not in lang_code_to_id: + raise ValueError( + f"""`tgt_lang={tgt_lang}` is not supported by this model. + Please specify a `tgt_lang` in {",".join(lang_code_to_id.keys())}. Note that SeamlessM4T supports + more languages for text translation than for speech synthesis.""" + ) + + kwargs_text, kwargs_speech = format_speech_generation_kwargs(kwargs) + kwargs_text["output_hidden_states"] = True + kwargs_text["return_dict_in_generate"] = True + kwargs_text["output_scores"] = True + + text_decoder_input_ids = kwargs_text.get("decoder_input_ids") + + # overwrite text_decoder_input_ids if tgt_lang is passed. The latter gets priority over decoder_input_ids. + text_tgt_lang_id = self.generation_config.text_decoder_lang_to_code_id.get(tgt_lang) + text_decoder_input_ids = torch.tensor([[text_tgt_lang_id]] * batch_size, device=self.device) + + kwargs_text["decoder_input_ids"] = text_decoder_input_ids + + # first generation + text_generation_output = super().generate(input_ids, **kwargs_text) + sequences = text_generation_output.sequences + + # prepare second generation + num_return_sequences = len(sequences) // batch_size + attention_mask = kwargs_speech.get("attention_mask", kwargs_text.get("attention_mask", None)) + + encoder_hidden_states = text_generation_output.encoder_hidden_states[-1] + + # take care of num_return_sequences + # take most probable hidden states per batch of return_sequences + # (batch_size*num_return_sequences, ...) -> (batch_size,...) + if num_return_sequences > 1: + idx_most_probable_sequences_per_batch = text_generation_output.sequences_scores.view(batch_size, -1) + idx_most_probable_sequences_per_batch = idx_most_probable_sequences_per_batch.argmax(-1) + idx_most_probable_sequences_per_batch = ( + idx_most_probable_sequences_per_batch + + torch.arange(batch_size, device=self.device) * num_return_sequences + ) + sequences = sequences[idx_most_probable_sequences_per_batch] + + # get decoder last hidden state - must do a pass through the text decoder + t2u_input_embeds = self.text_decoder( + input_ids=sequences, + encoder_hidden_states=encoder_hidden_states, + encoder_attention_mask=attention_mask, + ).last_hidden_state + + pad_token_id = self.generation_config.pad_token_id + + # Compute new attention mask + seq_lens = (sequences != pad_token_id).int().sum(1) + t2u_model_attention_mask = _compute_new_attention_mask(t2u_input_embeds, seq_lens) + kwargs_speech["attention_mask"] = t2u_model_attention_mask + + # Compute t2u decoder_input_ids + t2u_decoder_input_ids = kwargs_speech.get("decoder_input_ids") + t2u_tgt_lang_id = self.generation_config.t2u_lang_code_to_id.get(tgt_lang) + t2u_decoder_input_ids = torch.tensor( + [[self.config.t2u_eos_token_id, t2u_tgt_lang_id]] * batch_size, device=self.device + ) + kwargs_speech["decoder_input_ids"] = t2u_decoder_input_ids + # second generation + unit_ids = self.t2u_model.generate(inputs_embeds=t2u_input_embeds, **kwargs_speech) + output_unit_ids = unit_ids.detach().clone() + + # get rid of t2u_decoder_input_ids + unit_ids = unit_ids[:, kwargs_speech["decoder_input_ids"].shape[1] :] + # replace eos per pad + unit_ids[unit_ids == self.config.t2u_eos_token_id] = self.config.t2u_pad_token_id + # offset of control symbols + unit_ids = torch.where( + unit_ids == self.config.t2u_pad_token_id, unit_ids, unit_ids - self.config.vocoder_offset + ) + + vocoder_tgt_lang_id = self.generation_config.vocoder_lang_code_to_id.get(tgt_lang) + vocoder_tgt_lang_id = torch.tensor([[vocoder_tgt_lang_id]] * len(unit_ids), device=self.device) + + spkr_id = torch.tensor([[spkr_id]] * len(unit_ids), device=self.device) + + waveform, waveform_lengths = self.vocoder(input_ids=unit_ids, spkr_id=spkr_id, lang_id=vocoder_tgt_lang_id) + + if return_intermediate_token_ids: + return SeamlessM4TGenerationOutput( + waveform=waveform, + waveform_lengths=waveform_lengths, + sequences=sequences, + unit_sequences=output_unit_ids, + ) + + return waveform, waveform_lengths + + +@auto_docstring( + custom_intro=""" + The speech-to-speech SeamlessM4T Model transformer which can be used for S2ST. + """ +) +class SeamlessM4TForSpeechToSpeech(SeamlessM4TPreTrainedModel, GenerationMixin): + input_modalities = "audio" + output_modalities = ("audio",) + _keys_to_ignore_on_load_missing = ["text_encoder"] + main_input_name = "input_features" + + _tied_weights_keys = {"lm_head.weight": "shared.weight", "text_decoder.embed_tokens.weight": "shared.weight"} + + def __init__(self, config): + super().__init__(config) + + self.shared = nn.Embedding(config.vocab_size, config.hidden_size, config.pad_token_id) + self.speech_encoder = SeamlessM4TSpeechEncoder(config) + self.text_decoder = SeamlessM4TDecoder(config) + self.lm_head = nn.Linear(config.hidden_size, config.vocab_size, bias=False) + + self.t2u_model = SeamlessM4TTextToUnitForConditionalGeneration(config) + self.vocoder = SeamlessM4TCodeHifiGan(config) + self.post_init() + + def get_encoder(self): + return self.speech_encoder + + def get_decoder(self): + return self.text_decoder + + def get_input_embeddings(self): + return self.text_decoder.embed_tokens + + def set_input_embeddings(self, value): + self.text_decoder.embed_tokens = value + + @auto_docstring(custom_args=SEAMLESS_M4T_COMMON_CUSTOM_ARGS) + def forward( + self, + input_features: torch.LongTensor | None = None, + attention_mask: torch.Tensor | None = None, + decoder_input_ids: torch.LongTensor | None = None, + decoder_attention_mask: torch.LongTensor | None = None, + encoder_outputs: tuple[tuple[torch.FloatTensor]] | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.FloatTensor | None = None, + decoder_inputs_embeds: torch.FloatTensor | None = None, + labels: torch.LongTensor | None = None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + **kwargs, + ) -> Seq2SeqLMOutput | tuple[torch.FloatTensor]: + r""" + labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Labels for computing the masked language modeling loss. Indices should be in `[-100, 0, ..., + config.vocab_size]` (see `input_ids` docstring) Tokens with indices set to `-100` are ignored (masked), the + loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]` + """ + if labels is not None: + if use_cache: + logger.warning("The `use_cache` argument is changed to `False` since `labels` is provided.") + use_cache = False + if decoder_input_ids is None and decoder_inputs_embeds is None: + decoder_input_ids = shift_tokens_right( + labels, self.config.pad_token_id, self.config.decoder_start_token_id + ) + + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + use_cache = use_cache if use_cache is not None else self.config.use_cache + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + if encoder_outputs is None: + # if encoder_outputs is not None, it's probably used within a .generate method so no need to warn + logger.warning( + "This is the same forward method as `SeamlessM4TForSpeechToText`. It doesn't use `self.t2u_model`." + "If you want to generate speech, use the `generate` method." + ) + + encoder_outputs = self.speech_encoder( + input_features=input_features, + attention_mask=attention_mask, + inputs_embeds=inputs_embeds, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + # If the user passed a tuple for encoder_outputs, we wrap it in a BaseModelOutput when return_dict=True + elif return_dict and not isinstance(encoder_outputs, BaseModelOutput): + encoder_outputs = BaseModelOutput( + last_hidden_state=encoder_outputs[0], + hidden_states=encoder_outputs[1] if len(encoder_outputs) > 1 else None, + attentions=encoder_outputs[2] if len(encoder_outputs) > 2 else None, + ) + + encoder_attention_mask = attention_mask + if attention_mask is not None: + sub_sampled_lengths = self._compute_sub_sample_lengths_from_attention_mask(attention_mask).to( + encoder_outputs[0].device + ) + encoder_attention_mask = _compute_new_attention_mask( + hidden_states=encoder_outputs[0], seq_lens=sub_sampled_lengths + ) + + # decoder outputs consists of (dec_features, past_key_values, dec_hidden, dec_attn) + decoder_outputs = self.text_decoder( + input_ids=decoder_input_ids, + attention_mask=decoder_attention_mask, + encoder_hidden_states=encoder_outputs[0], + encoder_attention_mask=encoder_attention_mask, + past_key_values=past_key_values, + inputs_embeds=decoder_inputs_embeds, + use_cache=use_cache, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + + lm_logits = self.lm_head(decoder_outputs[0]) + + masked_lm_loss = None + if labels is not None: + loss_fct = CrossEntropyLoss() + labels = labels.to(lm_logits.device) + masked_lm_loss = loss_fct(lm_logits.view(-1, self.config.vocab_size), labels.view(-1)) + + if not return_dict: + outputs = decoder_outputs + encoder_outputs + output = (lm_logits,) + outputs[1:] + return ((masked_lm_loss,) + output) if masked_lm_loss is not None else output + + return Seq2SeqLMOutput( + loss=masked_lm_loss, + logits=lm_logits, + past_key_values=decoder_outputs.past_key_values, + decoder_hidden_states=decoder_outputs.hidden_states, + decoder_attentions=decoder_outputs.attentions, + cross_attentions=decoder_outputs.cross_attentions, + encoder_last_hidden_state=encoder_outputs.last_hidden_state, + encoder_hidden_states=encoder_outputs.hidden_states, + encoder_attentions=encoder_outputs.attentions, + ) + + @torch.no_grad() + def generate( + self, + input_features: torch.Tensor | None = None, + return_intermediate_token_ids: bool | None = None, + tgt_lang: str | None = None, + spkr_id: int | None = 0, + **kwargs, + ) -> torch.Tensor | SeamlessM4TGenerationOutput: + """ + Generates translated audio waveforms. + + + + This method successively calls the `.generate` function of two different sub-models. You can specify keyword + arguments at two different levels: general arguments that will be passed to both models, or prefixed arguments + that will be passed to one of them. + + For example, calling `.generate(input_features, num_beams=4, speech_do_sample=True)` will successively perform + beam-search decoding on the text model, and multinomial beam-search sampling on the speech model. + + For an overview of generation strategies and code examples, check out the [following + guide](./generation_strategies). + + + + Args: + input_features (`torch.FloatTensor` of shape `(batch_size, sequence_length, num_banks)`): + Input audio features. This should be returned by the [`SeamlessM4TFeatureExtractor`] class or the + [`SeamlessM4TProcessor`] class. See [`SeamlessM4TFeatureExtractor.__call__`] for details. + return_intermediate_token_ids (`bool`, *optional*): + If `True`, also returns the intermediate generated text and unit tokens. Set to `True` if you also want + to get translated text alongside the audio. + tgt_lang (`str`, *optional*): + The language to use as target language for translation. + spkr_id (`int`, *optional*, defaults to 0): + The id of the speaker used for speech synthesis. Must be lower than `config.vocoder_num_spkrs`. + + kwargs (*optional*): + Remaining dictionary of keyword arguments that will be passed to [`GenerationMixin.generate`]. Keyword + arguments are of two types: + + - Without a prefix, they will be entered as `**kwargs` for the `generate` method of each sub-model, + except for `decoder_input_ids` which will only be passed through the text components. + - With a *text_* or *speech_* prefix, they will be input for the `generate` method of the + text model and speech model respectively. It has the priority over the keywords without a prefix. + + This means you can, for example, specify a generation strategy for one generation but not for the + other. + + + Returns: + `Union[SeamlessM4TGenerationOutput, tuple[Tensor]]`: + - If `return_intermediate_token_ids`, returns [`SeamlessM4TGenerationOutput`]. + - If not `return_intermediate_token_ids`, returns a tuple composed of waveforms of shape `(batch_size, + sequence_length)` and `waveform_lengths` which gives the length of each sample. + """ + batch_size = len(input_features) if input_features is not None else len(kwargs.get("inputs_embeds")) + + if tgt_lang is None: + raise ValueError("You must specify a `tgt_lang` to generate translated speech.") + else: + # also accept __xxx__ + tgt_lang = tgt_lang.replace("__", "") + for key in ["text_decoder_lang_to_code_id", "t2u_lang_code_to_id", "vocoder_lang_code_to_id"]: + lang_code_to_id = getattr(self.generation_config, key, None) + if lang_code_to_id is None: + raise ValueError( + f"""This model generation config doesn't have a `{key}` key which maps the target language + to the right token id. Make sure to load the right generation config.""" + ) + elif tgt_lang not in lang_code_to_id: + raise ValueError( + f"""`tgt_lang={tgt_lang}` is not supported by this model. + Please specify a `tgt_lang` in {",".join(lang_code_to_id.keys())}. Note that SeamlessM4T supports + more languages for text translation than for speech synthesis.""" + ) + + kwargs_text, kwargs_speech = format_speech_generation_kwargs(kwargs) + kwargs_text["output_hidden_states"] = True + kwargs_text["return_dict_in_generate"] = True + kwargs_text["output_scores"] = True + + text_decoder_input_ids = kwargs_text.get("decoder_input_ids") + # overwrite text_decoder_input_ids if tgt_lang is passed. The latter gets priority over decoder_input_ids. + text_tgt_lang_id = self.generation_config.text_decoder_lang_to_code_id.get(tgt_lang) + text_decoder_input_ids = torch.tensor([[text_tgt_lang_id]] * batch_size, device=self.device) + + kwargs_text["decoder_input_ids"] = text_decoder_input_ids + + # first generation + text_generation_output = super().generate(input_features, **kwargs_text) + sequences = text_generation_output.sequences + + # prepare second generation + num_return_sequences = len(sequences) // batch_size + attention_mask = kwargs_speech.get("attention_mask", kwargs_text.get("attention_mask", None)) + + # get last_hidden_state from encoder + encoder_hidden_states = self.speech_encoder(input_features=input_features, attention_mask=attention_mask)[0] + + # input modality = speech so new attention mask for the decoder + if attention_mask is not None: + sub_sampled_lengths = self._compute_sub_sample_lengths_from_attention_mask(attention_mask).to( + encoder_hidden_states.device + ) + attention_mask = _compute_new_attention_mask( + hidden_states=encoder_hidden_states, seq_lens=sub_sampled_lengths + ) + + # take care of num_return_sequences + # take most probable hidden states per batch of return_sequences + # (batch_size*num_return_sequences, ...) -> (batch_size,...) + if num_return_sequences > 1: + idx_most_probable_sequences_per_batch = text_generation_output.sequences_scores.view(batch_size, -1) + idx_most_probable_sequences_per_batch = idx_most_probable_sequences_per_batch.argmax(-1) + idx_most_probable_sequences_per_batch = ( + idx_most_probable_sequences_per_batch + + torch.arange(batch_size, device=self.device) * num_return_sequences + ) + sequences = sequences[idx_most_probable_sequences_per_batch] + + # get decoder last hidden state - must do a pass through the text decoder + t2u_input_embeds = self.text_decoder( + input_ids=sequences, + encoder_hidden_states=encoder_hidden_states, + encoder_attention_mask=attention_mask, + ).last_hidden_state + + pad_token_id = self.generation_config.pad_token_id + + # Compute new attention mask + seq_lens = (sequences != pad_token_id).int().sum(1) + t2u_model_attention_mask = _compute_new_attention_mask(t2u_input_embeds, seq_lens) + kwargs_speech["attention_mask"] = t2u_model_attention_mask + + # Compute t2u decoder_input_ids + t2u_decoder_input_ids = kwargs_speech.get("decoder_input_ids") + t2u_tgt_lang_id = self.generation_config.t2u_lang_code_to_id.get(tgt_lang) + t2u_decoder_input_ids = torch.tensor( + [[self.config.t2u_eos_token_id, t2u_tgt_lang_id]] * batch_size, device=self.device + ) + kwargs_speech["decoder_input_ids"] = t2u_decoder_input_ids + + # second generation + unit_ids = self.t2u_model.generate(inputs_embeds=t2u_input_embeds, **kwargs_speech) + output_unit_ids = unit_ids.detach().clone() + + # get rid of t2u_decoder_input_ids + unit_ids = unit_ids[:, kwargs_speech["decoder_input_ids"].shape[1] :] + # replace eos per pad + unit_ids[unit_ids == self.config.t2u_eos_token_id] = self.config.t2u_pad_token_id + # offset of control symbols + unit_ids = torch.where( + unit_ids == self.config.t2u_pad_token_id, unit_ids, unit_ids - self.config.vocoder_offset + ) + + vocoder_tgt_lang_id = self.generation_config.vocoder_lang_code_to_id.get(tgt_lang) + vocoder_tgt_lang_id = torch.tensor([[vocoder_tgt_lang_id]] * len(unit_ids), device=self.device) + + spkr_id = torch.tensor([[spkr_id]] * len(unit_ids), device=self.device) + + waveform, waveform_lengths = self.vocoder(input_ids=unit_ids, spkr_id=spkr_id, lang_id=vocoder_tgt_lang_id) + + if return_intermediate_token_ids: + return SeamlessM4TGenerationOutput( + waveform=waveform, + waveform_lengths=waveform_lengths, + sequences=sequences, + unit_sequences=output_unit_ids, + ) + + return waveform, waveform_lengths + + +@auto_docstring( + custom_intro=""" + The original SeamlessM4T Model transformer which can be used for every tasks available (S2ST, S2TT, T2TT, T2ST). + """ +) +class SeamlessM4TModel(SeamlessM4TPreTrainedModel, GenerationMixin): + input_modalities = ("audio", "text") + output_modalities = ("audio", "text") + _tied_weights_keys = { + "lm_head.weight": "shared.weight", + "text_encoder.embed_tokens.weight": "shared.weight", + "text_decoder.embed_tokens.weight": "shared.weight", + } + + def __init__(self, config, current_modality="text"): + r""" + current_modality (`str`, *optional*, defaults to `"text"`): + Default modality. Used to initialize the model. + """ + super().__init__(config) + + self.shared = nn.Embedding(config.vocab_size, config.hidden_size, config.pad_token_id) + + self.text_encoder = SeamlessM4TEncoder(config) + self.speech_encoder = SeamlessM4TSpeechEncoder(config) + self.text_decoder = SeamlessM4TDecoder(config) + self.lm_head = nn.Linear(config.hidden_size, config.vocab_size, bias=False) + + self.current_modality = current_modality + if current_modality == "speech": + self.main_input_name = "input_features" + + # these models already call post_init in their initialization + self.t2u_model = SeamlessM4TTextToUnitForConditionalGeneration(config) + self.vocoder = SeamlessM4TCodeHifiGan(config) + + # Initialize weights and apply final processing + self.post_init() + + def set_modality(self, modality="text"): + if modality == "text": + self.main_input_name = "input_ids" + self.current_modality = "text" + elif modality == "speech": + self.main_input_name = "input_features" + self.current_modality = "speech" + else: + raise ValueError(f"`modality={modality}` is not a valid modality. It must be `text` or `speech`.") + + def get_encoder(self): + if self.current_modality == "text": + return self.text_encoder + else: + return self.speech_encoder + + def get_input_embeddings(self): + return self.text_decoder.embed_tokens + + def set_input_embeddings(self, value): + self.text_encoder.embed_tokens = value + self.text_decoder.embed_tokens = value + self.shared = value + + @auto_docstring(custom_args=SEAMLESS_M4T_COMMON_CUSTOM_ARGS) + def forward( + self, + input_ids: torch.LongTensor | None = None, + input_features: torch.FloatTensor | None = None, + attention_mask: torch.Tensor | None = None, + decoder_input_ids: torch.LongTensor | None = None, + decoder_attention_mask: torch.LongTensor | None = None, + encoder_outputs: tuple[tuple[torch.FloatTensor]] | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.FloatTensor | None = None, + decoder_inputs_embeds: torch.FloatTensor | None = None, + labels: torch.LongTensor | None = None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + **kwargs, + ) -> Seq2SeqLMOutput | tuple[torch.FloatTensor]: + r""" + labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Labels for computing the masked language modeling loss. Indices should be in `[-100, 0, ..., + config.vocab_size]` (see `input_ids` docstring) Tokens with indices set to `-100` are ignored (masked), the + loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]` + """ + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + use_cache = use_cache if use_cache is not None else self.config.use_cache + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + if labels is not None: + if use_cache: + logger.warning("The `use_cache` argument is changed to `False` since `labels` is provided.") + use_cache = False + if decoder_input_ids is None and decoder_inputs_embeds is None: + decoder_input_ids = shift_tokens_right( + labels, self.config.pad_token_id, self.config.decoder_start_token_id + ) + + if input_ids is None and input_features is None and inputs_embeds is None and encoder_outputs is None: + raise ValueError( + "`input_ids`,`input_features`, `inputs_embeds` and `encoder_outputs` are all empty. Make sure at least one of them is not." + ) + elif input_features is not None: + if input_ids is not None: + logger.warning( + "`input_ids` is not `None` but `input_features` has been given." + "`input_features` will be used in priority through the `speech_encoder`. " + "Make sure that `input_features` and `input_ids` are mutually exclusive." + ) + + if inputs_embeds is not None: + logger.warning( + "`inputs_embeds` is not `None` but `input_features` has been given." + "`input_features` will be used in priority through `speech_encoder`. " + "`inputs_embeds` will be ignored." + ) + + # if encoder_outputs is not None, it's probably used within a .generate method so no need to warn + logger.warning( + "This calls the same method `forward` as `SeamlessM4TForTextToText` and `SeamlessM4TForSpeechToText`" + "depending on the input modality. If you want to generate speech, use the `generate` method." + ) + + self.set_modality("speech") + + encoder_outputs = self.speech_encoder( + input_features=input_features, + attention_mask=attention_mask, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + + elif input_ids is not None or inputs_embeds is not None: + # if encoder_outputs is not None, it's probably used within a .generate method so no need to warn + logger.warning( + "This calls the same method `forward` as `SeamlessM4TForTextToText` and `SeamlessM4TForSpeechToText`" + "depending on the input modality. If you want to generate speech, use the `generate` method." + ) + self.set_modality("text") + encoder_outputs = self.text_encoder( + input_ids=input_ids, + attention_mask=attention_mask, + inputs_embeds=inputs_embeds, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + # If the user passed a tuple for encoder_outputs, we wrap it in a BaseModelOutput when return_dict=True + elif return_dict and not isinstance(encoder_outputs, BaseModelOutput): + encoder_outputs = BaseModelOutput( + last_hidden_state=encoder_outputs[0], + hidden_states=encoder_outputs[1] if len(encoder_outputs) > 1 else None, + attentions=encoder_outputs[2] if len(encoder_outputs) > 2 else None, + ) + + encoder_attention_mask = attention_mask + # input modality = speech so new attention mask + if self.current_modality == "speech" and attention_mask is not None: + sub_sampled_lengths = self._compute_sub_sample_lengths_from_attention_mask(attention_mask).to( + encoder_outputs[0].device + ) + encoder_attention_mask = _compute_new_attention_mask( + hidden_states=encoder_outputs[0], seq_lens=sub_sampled_lengths + ) + + # decoder outputs consists of (dec_features, past_key_values, dec_hidden, dec_attn) + decoder_outputs = self.text_decoder( + input_ids=decoder_input_ids, + attention_mask=decoder_attention_mask, + encoder_hidden_states=encoder_outputs[0], + encoder_attention_mask=encoder_attention_mask, + past_key_values=past_key_values, + inputs_embeds=decoder_inputs_embeds, + use_cache=use_cache, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + + lm_logits = self.lm_head(decoder_outputs[0]) + + masked_lm_loss = None + if labels is not None: + loss_fct = CrossEntropyLoss() + labels = labels.to(lm_logits.device) + masked_lm_loss = loss_fct(lm_logits.view(-1, self.config.vocab_size), labels.view(-1)) + + if not return_dict: + outputs = decoder_outputs + encoder_outputs + output = (lm_logits,) + outputs[1:] + return ((masked_lm_loss,) + output) if masked_lm_loss is not None else output + + return Seq2SeqLMOutput( + loss=masked_lm_loss, + logits=lm_logits, + past_key_values=decoder_outputs.past_key_values, + decoder_hidden_states=decoder_outputs.hidden_states, + decoder_attentions=decoder_outputs.attentions, + cross_attentions=decoder_outputs.cross_attentions, + encoder_last_hidden_state=encoder_outputs.last_hidden_state, + encoder_hidden_states=encoder_outputs.hidden_states, + encoder_attentions=encoder_outputs.attentions, + ) + + @torch.no_grad() + def generate( + self, + input_ids: torch.Tensor | None = None, + input_features: torch.Tensor | None = None, + return_intermediate_token_ids: bool | None = None, + tgt_lang: str | None = None, + spkr_id: int | None = 0, + generate_speech: bool | None = True, + **kwargs, + ) -> torch.Tensor | SeamlessM4TGenerationOutput: + """ + Generates translated token ids and/or translated audio waveforms. + + + + This method successively calls the `.generate` function of two different sub-models. You can specify keyword + arguments at two different levels: general arguments that will be passed to both models, or prefixed arguments + that will be passed to one of them. + + For example, calling `.generate(input_ids=input_ids, num_beams=4, speech_do_sample=True)` will successively + perform beam-search decoding on the text model, and multinomial beam-search sampling on the speech model. + + For an overview of generation strategies and code examples, check out the [following + guide](./generation_strategies). + + + + + Args: + input_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Indices of input sequence tokens in the vocabulary. + + Indices can be obtained using [`SeamlessM4TTokenizer`] or [`SeamlessM4TProcessor`]. See + [`PreTrainedTokenizer.encode`] and [`PreTrainedTokenizer.__call__`] for details. + + [What are input IDs?](../glossary#input-ids) + input_features (`torch.FloatTensor` of shape `(batch_size, sequence_length, num_banks)`, *optional*): + Input audio features. This should be returned by the [`SeamlessM4TFeatureExtractor`] class or the + [`SeamlessM4TProcessor`] class. See [`SeamlessM4TFeatureExtractor.__call__`] for details. + return_intermediate_token_ids (`bool`, *optional*): + If `True`, also returns the intermediate generated text and unit tokens. Set to `True` if you also want + to get translated text alongside the audio. + Note that if `generate_speech=False`, this parameter will be ignored and + the text tokens are returned. + tgt_lang (`str`, *optional*): + The language to use as target language for translation. + spkr_id (`int`, *optional*, defaults to 0): + The id of the speaker used for speech synthesis. Must be lower than `config.vocoder_num_spkrs`. + generate_speech (`bool`, *optional*, defaults to `True`): + If `False`, will only returns the text tokens and won't generate speech. + + kwargs (*optional*): + Remaining dictionary of keyword arguments that will be passed to [`GenerationMixin.generate`]. Keyword + arguments are of two types: + + - Without a prefix, they will be entered as `**kwargs` for the `generate` method of each sub-model, + except for `decoder_input_ids` which will only be passed through the text components. + - With a *text_* or *speech_* prefix, they will be input for the `generate` method of the + text model and speech model respectively. It has the priority over the keywords without a prefix. + + This means you can, for example, specify a generation strategy for one generation but not for the + other. + + Returns: + `Union[SeamlessM4TGenerationOutput, tuple[Tensor], ModelOutput]`: + - If `generate_speech` and `return_intermediate_token_ids`, returns [`SeamlessM4TGenerationOutput`]. + - If `generate_speech` and not `return_intermediate_token_ids`, returns a tuple composed of waveforms of + shape `(batch_size, sequence_length)` and `waveform_lengths` which gives the length of each sample. + - If `generate_speech=False`, it will returns `ModelOutput`. + """ + if input_ids is None and input_features is None and kwargs.get("inputs_embeds") is None: + raise ValueError( + "`input_ids`,`input_features` and `inputs_embeds` are all empty. Make sure at least one of them is not." + ) + + if generate_speech and tgt_lang is None: + raise ValueError("You must specify a `tgt_lang` to generate translated speech.") + + if tgt_lang is not None: + # also accept __xxx__ + tgt_lang = tgt_lang.replace("__", "") + for key in ["text_decoder_lang_to_code_id", "t2u_lang_code_to_id", "vocoder_lang_code_to_id"]: + lang_code_to_id = getattr(self.generation_config, key, None) + if lang_code_to_id is None: + raise ValueError( + f"""This model generation config doesn't have a `{key}` key which maps the target language + to the right token id. Make sure to load the right generation config.""" + ) + elif tgt_lang not in lang_code_to_id: + raise ValueError( + f"""`tgt_lang={tgt_lang}` is not supported by this model. + Please specify a `tgt_lang` in {",".join(lang_code_to_id.keys())}. Note that SeamlessM4T supports + more languages for text translation than for speech synthesis.""" + ) + + batch_size = ( + len(input_features) + if input_features is not None + else (len(input_ids) if input_ids is not None else len(kwargs.get("inputs_embeds"))) + ) + + kwargs_text, kwargs_speech = format_speech_generation_kwargs(kwargs) + kwargs_text["output_hidden_states"] = True + kwargs_text["return_dict_in_generate"] = True + kwargs_text["output_scores"] = True + + text_decoder_input_ids = kwargs_text.get("decoder_input_ids") + # overwrite text_decoder_input_ids if tgt_lang is passed. The latter gets priority over decoder_input_ids. + if tgt_lang is not None: + # tgt_lang gets priority over decoder input ids + text_tgt_lang_id = self.generation_config.text_decoder_lang_to_code_id.get(tgt_lang) + text_decoder_input_ids = torch.tensor([[text_tgt_lang_id]] * batch_size, device=self.device) + + kwargs_text["decoder_input_ids"] = text_decoder_input_ids + + # first generation + if input_features is not None: + self.set_modality("speech") + if input_ids is not None: + logger.warning( + "`input_features` and `input_ids` are both non empty. `input_features` will be used in priority " + "through the speech encoder. Make sure `input_features=None` if you want to use the text encoder." + ) + text_generation_output = super().generate(input_features=input_features, **kwargs_text) + else: + self.set_modality("text") + text_generation_output = super().generate(input_ids=input_ids, input_features=None, **kwargs_text) + sequences = text_generation_output.sequences + + if not generate_speech: + return text_generation_output + + # prepare second generation + num_return_sequences = len(sequences) // batch_size + attention_mask = kwargs_speech.get("attention_mask", kwargs_text.get("attention_mask", None)) + + # get encoder last hidden states + if self.current_modality == "speech": + # get last_hidden_state from encoder - must do a pass through the speech encoder + encoder_hidden_states = self.speech_encoder( + input_features=input_features, attention_mask=attention_mask + ).last_hidden_state + + # input modality = speech so new attention mask for the decoder + if attention_mask is not None: + sub_sampled_lengths = self._compute_sub_sample_lengths_from_attention_mask(attention_mask).to( + encoder_hidden_states.device + ) + attention_mask = _compute_new_attention_mask( + hidden_states=encoder_hidden_states, seq_lens=sub_sampled_lengths + ) + else: + encoder_hidden_states = text_generation_output.encoder_hidden_states[-1] + + # take care of num_return_sequences + # take most probable hidden states per batch of return_sequences + # (batch_size*num_return_sequences, ...) -> (batch_size,...) + if num_return_sequences > 1: + idx_most_probable_sequences_per_batch = text_generation_output.sequences_scores.view(batch_size, -1) + idx_most_probable_sequences_per_batch = idx_most_probable_sequences_per_batch.argmax(-1) + idx_most_probable_sequences_per_batch = ( + idx_most_probable_sequences_per_batch + + torch.arange(batch_size, device=self.device) * num_return_sequences + ) + sequences = sequences[idx_most_probable_sequences_per_batch] + + # get decoder last hidden state - must do a pass through the text decoder + t2u_input_embeds = self.text_decoder( + input_ids=sequences, + encoder_hidden_states=encoder_hidden_states, + encoder_attention_mask=attention_mask, + ).last_hidden_state + + pad_token_id = self.generation_config.pad_token_id + + # Compute new attention mask + seq_lens = (sequences != pad_token_id).int().sum(1) + t2u_model_attention_mask = _compute_new_attention_mask(t2u_input_embeds, seq_lens) + kwargs_speech["attention_mask"] = t2u_model_attention_mask + + # Compute t2u decoder_input_ids + t2u_decoder_input_ids = kwargs_speech.get("decoder_input_ids") + t2u_tgt_lang_id = self.generation_config.t2u_lang_code_to_id.get(tgt_lang) + t2u_decoder_input_ids = torch.tensor( + [[self.config.t2u_eos_token_id, t2u_tgt_lang_id]] * batch_size, device=self.device + ) + kwargs_speech["decoder_input_ids"] = t2u_decoder_input_ids + + # second generation + unit_ids = self.t2u_model.generate(inputs_embeds=t2u_input_embeds, **kwargs_speech) + output_unit_ids = unit_ids.detach().clone() + + # get rid of t2u_decoder_input_ids + unit_ids = unit_ids[:, kwargs_speech["decoder_input_ids"].shape[1] :] + # replace eos per pad + unit_ids[unit_ids == self.config.t2u_eos_token_id] = self.config.t2u_pad_token_id + # offset of control symbols + unit_ids = torch.where( + unit_ids == self.config.t2u_pad_token_id, unit_ids, unit_ids - self.config.vocoder_offset + ) + + vocoder_tgt_lang_id = self.generation_config.vocoder_lang_code_to_id.get(tgt_lang) + vocoder_tgt_lang_id = torch.tensor([[vocoder_tgt_lang_id]] * len(unit_ids), device=self.device) + + spkr_id = torch.tensor([[spkr_id]] * len(unit_ids), device=self.device) + + waveform, waveform_lengths = self.vocoder(input_ids=unit_ids, spkr_id=spkr_id, lang_id=vocoder_tgt_lang_id) + + if return_intermediate_token_ids: + return SeamlessM4TGenerationOutput( + waveform=waveform, + waveform_lengths=waveform_lengths, + sequences=sequences, + unit_sequences=output_unit_ids, + ) + + return waveform, waveform_lengths + + +__all__ = [ + "SeamlessM4TForTextToSpeech", + "SeamlessM4TForSpeechToSpeech", + "SeamlessM4TForTextToText", + "SeamlessM4TForSpeechToText", + "SeamlessM4TModel", + "SeamlessM4TPreTrainedModel", + "SeamlessM4TCodeHifiGan", + "SeamlessM4THifiGan", + "SeamlessM4TTextToUnitForConditionalGeneration", + "SeamlessM4TTextToUnitModel", +] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/seamless_m4t/processing_seamless_m4t.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/seamless_m4t/processing_seamless_m4t.py new file mode 100644 index 0000000000000000000000000000000000000000..21b5d253a4f08d2cd5f75f9af34417952dae93d4 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/seamless_m4t/processing_seamless_m4t.py @@ -0,0 +1,78 @@ +# Copyright 2023 The HuggingFace Inc. team. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +""" +Audio/Text processor class for SeamlessM4T +""" + +from ...audio_utils import AudioInput +from ...processing_utils import ProcessingKwargs, ProcessorMixin, TextKwargs, Unpack +from ...tokenization_utils_base import PreTokenizedInput, TextInput +from ...utils import auto_docstring, logging + + +logger = logging.get_logger(__name__) + + +class SeamlessM4TTextKwargs(TextKwargs): + """ + src_lang (`str`, *optional*): + The source language code for the input text (e.g., "eng" for English, "fra" for French). This is used + to set the language token at the beginning of the input sequence, which helps the model understand the + input language for translation or transcription tasks. + tgt_lang (`str`, *optional*): + The target language code for the output (e.g., "eng" for English, "fra" for French). This is used to + specify the desired output language for translation tasks. The model will generate text in this language. + """ + + src_lang: str | None + tgt_lang: str | None + + +class SeamlessM4TProcessorKwargs(ProcessingKwargs, total=False): + text_kwargs: SeamlessM4TTextKwargs + _defaults = {} + + +@auto_docstring +class SeamlessM4TProcessor(ProcessorMixin): + valid_processor_kwargs = SeamlessM4TProcessorKwargs + + def __init__(self, feature_extractor, tokenizer): + super().__init__(feature_extractor, tokenizer) + + @auto_docstring + def __call__( + self, + text: TextInput | PreTokenizedInput | list[TextInput] | list[PreTokenizedInput] | None = None, + audio: AudioInput | None = None, + **kwargs: Unpack[ProcessingKwargs], + ): + r""" + Returns: + [`BatchEncoding`]: A [`BatchEncoding`] with the following fields: + + - **input_ids** -- List of token ids to be fed to a model. Returned when `text` is not `None`. + - **attention_mask** -- List of indices specifying which tokens should be attended to by the model (when + `return_attention_mask=True` or if *"attention_mask"* is in `self.model_input_names` and if `text` is not + `None`). + - **input_features** -- Audio input features to be fed to a model. Returned when `audios` is not `None`. + """ + if text is not None and audio is not None: + raise ValueError( + "Text and audios are mututally exclusive when passed to `SeamlessM4T`. Specify one or another." + ) + return super().__call__(text=text, audio=audio, **kwargs) + + +__all__ = ["SeamlessM4TProcessor"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/seamless_m4t/tokenization_seamless_m4t.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/seamless_m4t/tokenization_seamless_m4t.py new file mode 100644 index 0000000000000000000000000000000000000000..863f91070c5de05250b6dbc2aaa75cfde8a8e736 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/seamless_m4t/tokenization_seamless_m4t.py @@ -0,0 +1,427 @@ +# Copyright 2023 The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""Tokenization class for SeamlessM4T.""" + +from tokenizers import Regex, Tokenizer, decoders, normalizers, pre_tokenizers, processors +from tokenizers.models import BPE + +from ...tokenization_python import ( + BatchEncoding, + PreTokenizedInput, + TextInput, +) +from ...tokenization_utils_tokenizers import TokenizersBackend +from ...utils import PaddingStrategy, logging + + +logger = logging.get_logger(__name__) + +VOCAB_FILES_NAMES = {"vocab_file": "sentencepiece.bpe.model", "tokenizer_file": "tokenizer.json"} + + +class SeamlessM4TTokenizer(TokenizersBackend): + """ + Construct a SeamlessM4T tokenizer (backed by HuggingFace's *tokenizers* library). Based on + [BPE](https://huggingface.co/docs/tokenizers/python/latest/components.html?highlight=bpe#models). + + This tokenizer inherits from [`TokenizersBackend`] which contains most of the main methods. Users should + refer to this superclass for more information regarding those methods. + + The tokenization method is ` ` for source language documents, and ` ` for target language documents. + + Examples: + + ```python + >>> from transformers import SeamlessM4TTokenizer + + >>> tokenizer = SeamlessM4TTokenizer.from_pretrained( + ... "facebook/hf-seamless-m4t-medium", src_lang="eng", tgt_lang="fra" + ... ) + >>> example_english_phrase = " UN Chief Says There Is No Military Solution in Syria" + >>> expected_translation_french = "Le chef de l'ONU affirme qu'il n'y a pas de solution militaire en Syrie." + >>> inputs = tokenizer(example_english_phrase, text_target=expected_translation_french, return_tensors="pt") + ``` + + Args: + vocab (`list` or `dict`, *optional*): + List of (token, score) tuples or dict mapping tokens to indices. If not provided, uses default vocab. + merges (`str` or `list`, *optional*): + List of merge rules for BPE model. If not provided, uses empty list. + bos_token (`str`, *optional*, defaults to `""`): + The beginning of sequence token that was used during pretraining. Can be used a sequence classifier token. + + + + When building a sequence using special tokens, this is not the token that is used for the beginning of + sequence. The token used is the `cls_token`. + + + + eos_token (`str`, *optional*, defaults to `""`): + The end of sequence token. + + + + When building a sequence using special tokens, this is not the token that is used for the end of sequence. + The token used is the `sep_token`. + + + + sep_token (`str`, *optional*, defaults to `""`): + The separator token, which is used when building a sequence from multiple sequences, e.g. two sequences for + sequence classification or for a text and a question for question answering. It is also used as the last + token of a sequence built with special tokens. + cls_token (`str`, *optional*, defaults to `""`): + The classifier token which is used when doing sequence classification (classification of the whole sequence + instead of per-token classification). It is the first token of the sequence when built with special tokens. + unk_token (`str`, *optional*, defaults to `""`): + The unknown token. A token that is not in the vocabulary cannot be converted to an ID and is set to be this + token instead. + pad_token (`str`, *optional*, defaults to `""`): + The token used for padding, for example when batching sequences of different lengths. + src_lang (`str`, *optional*, defaults to `"eng"`): + The language to use as source language for translation. + tgt_lang (`str`, *optional*, defaults to `"fra"`): + The language to use as target language for translation. + additional_special_tokens (tuple or list of `str` or `tokenizers.AddedToken`, *optional*): + A tuple or a list of additional special tokens. + """ + + vocab_files_names = VOCAB_FILES_NAMES + model_input_names = ["input_ids", "attention_mask"] + model = BPE + + prefix_tokens: list[int] = None + suffix_tokens: list[int] = None + + def __init__( + self, + vocab: str | dict[str, int] | None = None, + merges: str | list[str] | None = None, + bos_token="", + eos_token="", + sep_token="", + cls_token="", + unk_token="", + pad_token="", + src_lang="eng", + tgt_lang="fra", + additional_special_tokens=None, + keep_accents=None, + vocab_file=None, + **kwargs, + ): + self._vocab = vocab or { + str(pad_token): 0, + str(unk_token): 1, + str(bos_token): 2, + str(eos_token): 3, + } + + self._merges = merges or [] + self._tokenizer = Tokenizer( + BPE( + vocab=self._vocab, + merges=self._merges, + dropout=None, + unk_token=str(unk_token), + fuse_unk=True, + byte_fallback=False, + ) + ) + + self._tokenizer.normalizer = normalizers.Sequence( + [ + normalizers.Replace(Regex(r"[\n\r\t]"), " "), + normalizers.NFKC(), + normalizers.Strip(left=False, right=True), + normalizers.Replace(Regex(r" +▁"), "▁"), + normalizers.Replace(Regex(r"^▁+$"), ""), + normalizers.Replace(Regex(r" {2,}"), "▁"), + ] + ) + + self._tokenizer.pre_tokenizer = pre_tokenizers.Metaspace(replacement="▁", prepend_scheme="first", split=True) + + self._tokenizer.decoder = decoders.Metaspace(replacement="▁", prepend_scheme="first", split=True) + + if "__" not in src_lang: + src_lang = f"__{src_lang}__" + if "__" not in tgt_lang: + tgt_lang = f"__{tgt_lang}__" + + # V5: Convert additional_special_tokens parameter to extra_special_tokens for backward compatibility + # PreTrainedTokenizerBase.__init__() will handle the conversion, but we need to pass it via kwargs + if additional_special_tokens is not None: + kwargs.setdefault("additional_special_tokens", additional_special_tokens) + + super().__init__( + bos_token=bos_token, + eos_token=eos_token, + sep_token=sep_token, + cls_token=cls_token, + unk_token=unk_token, + pad_token=pad_token, + src_lang=src_lang, + tgt_lang=tgt_lang, + keep_accents=keep_accents, + vocab_file=vocab_file, + **kwargs, + ) + + # Build fairseq mappings + self.fairseq_offset = 1 + self.fairseq_tokens_to_ids = { + "": 0, + "": 1, + "": 2, + "": 3, + } + self.fairseq_ids_to_tokens = {v: k for k, v in self.fairseq_tokens_to_ids.items()} + + self._src_lang = src_lang + self._tgt_lang = tgt_lang + + self.set_tgt_lang_special_tokens(self._tgt_lang) + + @classmethod + def convert_from_spm_model(cls, vocab, **kwargs): + """When converting from spm, offset is needed to account for special tokens.""" + _vocab = { + "": 0, + "": 1, + "": 2, + "": 3, + } + for i, token in enumerate(list(vocab.keys())): + _vocab[token] = i + 1 # offset by 1 to account for special tokens + kwargs["vocab"] = _vocab + return kwargs + + @property + def src_lang(self) -> str: + return self._src_lang + + @src_lang.setter + def src_lang(self, new_src_lang: str) -> None: + if "__" not in new_src_lang: + self._src_lang = f"__{new_src_lang}__" + else: + self._src_lang = new_src_lang + self.set_src_lang_special_tokens(self._src_lang) + + @property + def tgt_lang(self) -> str: + return self._tgt_lang + + @tgt_lang.setter + def tgt_lang(self, new_tgt_lang: str) -> None: + if "__" not in new_tgt_lang: + self._tgt_lang = f"__{new_tgt_lang}__" + else: + self._tgt_lang = new_tgt_lang + self.set_tgt_lang_special_tokens(self._tgt_lang) + + def _build_translation_inputs( + self, raw_inputs, return_tensors: str, src_lang: str | None, tgt_lang: str | None, **extra_kwargs + ): + """Used by translation pipeline, to prepare inputs for the generate function""" + if src_lang is None or tgt_lang is None: + raise ValueError("Translation requires a `src_lang` and a `tgt_lang` for this model") + self.src_lang = src_lang + inputs = self(raw_inputs, add_special_tokens=True, return_tensors=return_tensors, **extra_kwargs) + if "__" not in tgt_lang: + tgt_lang = f"__{tgt_lang}__" + tgt_lang_id = self.convert_tokens_to_ids(tgt_lang) + inputs["forced_bos_token_id"] = tgt_lang_id + return inputs + + def prepare_seq2seq_batch( + self, + src_texts: list[str], + src_lang: str = "eng", + tgt_texts: list[str] | None = None, + tgt_lang: str = "fra", + max_length: int | None = None, + max_target_length: int | None = None, + padding: str = "longest", + return_tensors: str | None = None, + truncation: bool = True, + **kwargs, + ) -> BatchEncoding: + self.src_lang = src_lang + self.tgt_lang = tgt_lang + + if max_length is None: + max_length = self.model_max_length + + model_inputs = self( + src_texts, + add_special_tokens=True, + return_tensors=return_tensors, + max_length=max_length, + padding=padding, + truncation=truncation, + **kwargs, + ) + + if tgt_texts is None: + return model_inputs + + # Process tgt_texts + if max_target_length is None: + max_target_length = max_length + + self._switch_to_target_mode() + labels = self( + tgt_texts, + add_special_tokens=True, + return_tensors=return_tensors, + padding=padding, + max_length=max_target_length, + truncation=truncation, + **kwargs, + ) + model_inputs["labels"] = labels["input_ids"] + + self._switch_to_input_mode() + + return model_inputs + + def _switch_to_input_mode(self): + return self.set_src_lang_special_tokens(self.src_lang) + + def _switch_to_target_mode(self): + return self.set_tgt_lang_special_tokens(self.tgt_lang) + + def set_src_lang_special_tokens(self, src_lang) -> None: + """Reset the special tokens to the source lang setting. + Prefix=[src_lang_code], suffix = [eos] + """ + self.cur_lang_code = self.convert_tokens_to_ids(src_lang) + + if self.cur_lang_code == self.unk_token_id: + logger.warning_once( + f"`src_lang={src_lang}` has not be found in the `vocabulary`. Behaviour will probably be unexpected because the language token id will be replaced by the unknown token id." + ) + + self.prefix_tokens = [self.cur_lang_code] + self.suffix_tokens = [self.eos_token_id] + + prefix_tokens_str = self.convert_ids_to_tokens(self.prefix_tokens) + suffix_tokens_str = self.convert_ids_to_tokens(self.suffix_tokens) + + self._tokenizer.post_processor = processors.TemplateProcessing( + single=prefix_tokens_str + ["$A"] + suffix_tokens_str, + pair=prefix_tokens_str + ["$A", "$B"] + suffix_tokens_str, + special_tokens=list(zip(prefix_tokens_str + suffix_tokens_str, self.prefix_tokens + self.suffix_tokens)), + ) + + def set_tgt_lang_special_tokens(self, lang: str) -> None: + """Reset the special tokens to the target lang setting. + Prefix=[eos, tgt_lang_code] and suffix=[eos]. + """ + self.cur_lang_code = self.convert_tokens_to_ids(lang) + + if self.cur_lang_code == self.unk_token_id: + logger.warning_once( + f"`tgt_lang={lang}` has not be found in the `vocabulary`. Behaviour will probably be unexpected because the language token id will be replaced by the unknown token id." + ) + + self.prefix_tokens = [self.eos_token_id, self.cur_lang_code] + self.suffix_tokens = [self.eos_token_id] + + prefix_tokens_str = self.convert_ids_to_tokens(self.prefix_tokens) + suffix_tokens_str = self.convert_ids_to_tokens(self.suffix_tokens) + + self._tokenizer.post_processor = processors.TemplateProcessing( + single=prefix_tokens_str + ["$A"] + suffix_tokens_str, + pair=prefix_tokens_str + ["$A", "$B"] + suffix_tokens_str, + special_tokens=list(zip(prefix_tokens_str + suffix_tokens_str, self.prefix_tokens + self.suffix_tokens)), + ) + + def __call__( + self, + text: TextInput | PreTokenizedInput | list[TextInput] | list[PreTokenizedInput] | None = None, + text_pair: TextInput | PreTokenizedInput | list[TextInput] | list[PreTokenizedInput] | None = None, + text_target: TextInput | PreTokenizedInput | list[TextInput] | list[PreTokenizedInput] | None = None, + text_pair_target: TextInput | PreTokenizedInput | list[TextInput] | list[PreTokenizedInput] | None = None, + padding: bool | str | PaddingStrategy = False, + pad_to_multiple_of: int | None = None, + src_lang: str | None = None, + tgt_lang: str | None = None, + **kwargs, + ): + """ + Args: + text (`str`, `list[str]`, `list[list[str]]`, *optional*): + The sequence or batch of sequences to be encoded. Each sequence can be a string or a list of strings + (pretokenized string). If the sequences are provided as list of strings (pretokenized), you must set + `is_split_into_words=True` (to lift the ambiguity with a batch of sequences). + text_pair (`str`, `list[str]`, `list[list[str]]`, *optional*): + The sequence or batch of sequences to be encoded. Each sequence can be a string or a list of strings + (pretokenized string). If the sequences are provided as list of strings (pretokenized), you must set + `is_split_into_words=True` (to lift the ambiguity with a batch of sequences). + text_target (`str`, `list[str]`, `list[list[str]]`, *optional*): + The sequence or batch of sequences to be encoded as target texts. Each sequence can be a string or a + list of strings (pretokenized string). If the sequences are provided as list of strings (pretokenized), + you must set `is_split_into_words=True` (to lift the ambiguity with a batch of sequences). + text_pair_target (`str`, `list[str]`, `list[list[str]]`, *optional*): + The sequence or batch of sequences to be encoded as target texts. Each sequence can be a string or a + list of strings (pretokenized string). If the sequences are provided as list of strings (pretokenized), + you must set `is_split_into_words=True` (to lift the ambiguity with a batch of sequences). + padding (`bool`, `str` or [`~utils.PaddingStrategy`], *optional*, defaults to `False`): + Select a strategy to pad the returned sequences (according to the model's padding side and padding + index) among: + + - `True` or `'longest'`: Pad to the longest sequence in the batch (or no padding if only a single + sequence if provided). + - `'max_length'`: Pad to a maximum length specified with the argument `max_length` or to the maximum + acceptable input length for the model if that argument is not provided. + - `False` or `'do_not_pad'` (default): No padding (i.e., can output a batch with sequences of different + lengths). + pad_to_multiple_of (`int`, *optional*, defaults to `None`): + If set will pad the sequence to a multiple of the provided value. + + This is especially useful to enable the use of Tensor Cores on NVIDIA hardware with compute capability + `>= 7.5` (Volta). + src_lang (`str`, *optional*): + A string representing the source language. If not specified, the last `src_lang` specified (either + during initialization or when calling this tokenizer) will be used. + tgt_lang (`str`, *optional*): + A string representing the target language. If not specified, the last `tgt_lang` specified (either + during initialization or when calling this tokenizer) will be used. + kwargs (*optional*): + Remaining dictionary of keyword arguments that will be passed to [`TokenizersBackend.__call__`]. + """ + if src_lang is not None: + self.src_lang = src_lang + if tgt_lang is not None: + self.tgt_lang = tgt_lang + + output = super().__call__( + text=text, + text_pair=text_pair, + text_target=text_target, + text_pair_target=text_pair_target, + padding=padding, + pad_to_multiple_of=pad_to_multiple_of, + **kwargs, + ) + + return output + + +__all__ = ["SeamlessM4TTokenizer"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/seamless_m4t_v2/__init__.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/seamless_m4t_v2/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..10f256f8575595d6b3409c030e1d6c3b33c75aa9 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/seamless_m4t_v2/__init__.py @@ -0,0 +1,27 @@ +# Copyright 2024 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from typing import TYPE_CHECKING + +from ...utils import _LazyModule +from ...utils.import_utils import define_import_structure + + +if TYPE_CHECKING: + from .configuration_seamless_m4t_v2 import * + from .modeling_seamless_m4t_v2 import * +else: + import sys + + _file = globals()["__file__"] + sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__) diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/seamless_m4t_v2/configuration_seamless_m4t_v2.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/seamless_m4t_v2/configuration_seamless_m4t_v2.py new file mode 100644 index 0000000000000000000000000000000000000000..46a1114f01e97730870044fb89dfe3b8c1ca8db4 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/seamless_m4t_v2/configuration_seamless_m4t_v2.py @@ -0,0 +1,423 @@ +# Copyright 2023 The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""SeamlessM4Tv2 model configuration""" + +from ...configuration_utils import PreTrainedConfig +from ...utils import logging + + +logger = logging.get_logger(__name__) + + +class SeamlessM4Tv2Config(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`~SeamlessM4Tv2Model`]. It is used to instantiate + an SeamlessM4Tv2 model according to the specified arguments, defining the model architecture. Instantiating a + configuration with the defaults will yield a similar configuration to that of the SeamlessM4Tv2 + [""](https://huggingface.co/"") architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + + Args: + vocab_size (`int`, *optional*, defaults to 256102): + Vocabulary size of the text modality of the SeamlessM4Tv2 model. Defines the number of different tokens + that can be represented by the `inputs_ids` passed when calling [`~SeamlessM4Tv2Model`], + [`~SeamlessM4Tv2ForTextToSpeech`] or [`~SeamlessM4Tv2ForTextToText`]. + t2u_vocab_size (`int`, *optional*, defaults to 10082): + Unit vocabulary size of the SeamlessM4Tv2 model. Defines the number of different "unit tokens" that can be + represented by the `inputs_ids` passed when calling the Text-To-Units sub-model of [`~SeamlessM4Tv2Model`], + [`~SeamlessM4Tv2ForSpeechToSpeech`] or [`~SeamlessM4Tv2ForTextToSpeech`]. + char_vocab_size (`int`, *optional*, defaults to 10943): + Character vocabulary size of the SeamlessM4Tv2 model. Defines the number of different character tokens that + can be represented by the `char_inputs_ids` passed when calling the Text-To-Units sub-model of + [`~SeamlessM4Tv2Model`], [`~SeamlessM4Tv2ForSpeechToSpeech`] or [`~SeamlessM4Tv2ForTextToSpeech`]. + + > Parameters shared across sub-models + + hidden_size (`int`, *optional*, defaults to 1024): + Dimensionality of the "intermediate" layers in the architecture. + initializer_range (`float`, *optional*, defaults to 0.02): + The standard deviation of the truncated_normal_initializer for initializing all weight matrices. + layer_norm_eps (`float`, *optional*, defaults to 1e-05): + The epsilon used by the layer normalization layers. + use_cache (`bool`, *optional*, defaults to `True`): + Whether or not the model should return the last key/values attentions (not used by all models). + max_position_embeddings (`int`, *optional*, defaults to 4096): + The maximum sequence length that this model text encoder and decoder might ever be used with. Typically set + this to something large just in case (e.g., 512 or 1024 or 2048). + is_encoder_decoder (`bool`, *optional*, defaults to `True`): + Whether the model is used as an encoder/decoder or not. + encoder_layerdrop (`float`, *optional*, defaults to 0.05): + The LayerDrop probability for the encoders. See the [LayerDrop paper](see https://huggingface.co/papers/1909.11556) + for more details. + decoder_layerdrop (`float`, *optional*, defaults to 0.05): + The LayerDrop probability for the decoders. See the [LayerDrop paper](see https://huggingface.co/papers/1909.11556) + for more details. + activation_function (`str` or `function`, *optional*, defaults to `"relu"`): + The non-linear activation function (function or string) in the decoder and feed-forward layers. If string, + `"gelu"`, `"relu"`, `"selu"`, `"swish"` and `"gelu_new"` are supported. + dropout (`float`, *optional*, defaults to 0.1): + The dropout probability for all fully connected layers in the embeddings, encoder, decoder, and pooler. + attention_dropout (`float`, *optional*, defaults to 0.1): + The dropout probability for all attention layers. + activation_dropout (`float`, *optional*, defaults to 0.0): + The dropout probability for all activation layers in the model. + scale_embedding (`bool`, *optional*, defaults to `True`): + Scale embeddings by diving by sqrt(d_model). + + > Text encoder and text decoder specific parameters + + encoder_layers (`int`, *optional*, defaults to 24): + Number of hidden layers in the Transformer text encoder. + encoder_ffn_dim (`int`, *optional*, defaults to 8192): + Dimension of the "intermediate" (i.e., feed-forward) layer in the Transformer text encoder. + encoder_attention_heads (`int`, *optional*, defaults to 16): + Number of attention heads for each attention layer in the Transformer text encoder. + decoder_layers (`int`, *optional*, defaults to 24): + Number of hidden layers in the Transformer text decoder. + decoder_ffn_dim (`int`, *optional*, defaults to 8192): + Dimension of the "intermediate" (i.e., feed-forward) layer in the Transformer text decoder. + decoder_attention_heads (`int`, *optional*, defaults to 16): + Number of attention heads for each attention layer in the Transformer text decoder. + decoder_start_token_id (`int`, *optional*, defaults to 3): + If an encoder-decoder model starts decoding with a different token than _bos_, the id of that token. Only + applied in the text decoder. + max_new_tokens (`int`, *optional*, defaults to 256): + The maximum numbers of text tokens to generate, ignoring the number of tokens in the prompt. + pad_token_id (`int`, *optional*, defaults to 0): + The id of the _padding_ text token. Only applied to the text-decoder model. + bos_token_id (`int`, *optional*, defaults to 2): + The id of the _beginning-of-stream_ text token. Only applied to the text-decoder model. + eos_token_id (`int`, *optional*, defaults to 3): + The id of the _end-of-stream_ text token. Only applied to the text-decoder model. + + > Speech encoder specific parameters + + speech_encoder_layers (`int`, *optional*, defaults to 24): + Number of hidden layers in the Transformer speech encoder. + speech_encoder_attention_heads (`int`, *optional*, defaults to 16): + Number of attention heads for each attention layer in the Transformer speech encoder. + speech_encoder_intermediate_size (`int`, *optional*, defaults to 4096): + Dimension of the "intermediate" (i.e., feed-forward) layer in the Transformer speech encoder. + speech_encoder_hidden_act (`str` or `function`, *optional*, defaults to `"swish"`): + The non-linear activation function (function or string) in the speech encoder. If string, `"gelu"`, + `"relu"`, `"selu"`, `"swish"` and `"gelu_new"` are supported. + speech_encoder_dropout (`float`, *optional*, defaults to 0.0): + The dropout probability for all layers in the speech encoder. + add_adapter (`bool`, *optional*, defaults to `True`): + Add an adapter layer on top of the speech encoder. + speech_encoder_layerdrop (`float`, *optional*, defaults to 0.1): + The LayerDrop probability for the speech encoder. See the [LayerDrop paper](see + https://huggingface.co/papers/1909.11556) for more details. + feature_projection_input_dim (`int`, *optional*, defaults to 160): + Input dimension of the input feature projection of the speech encoder, i.e the dimension after processing + input audios with [`SeamlessM4TFeatureExtractor`]. + adaptor_kernel_size (`int`, *optional*, defaults to 8): + Kernel size of the convolutional layers in the adapter network. Only relevant if `add_adapter is True`. + adaptor_stride (`int`, *optional*, defaults to 8): + Stride of the convolutional layers in the adapter network. Only relevant if `add_adapter is True`. + adaptor_dropout (`float`, *optional*, defaults to 0.1): + The dropout probability for all layers in the speech adapter. + num_adapter_layers (`int`, *optional*, defaults to 1): + Number of convolutional layers that should be used in the adapter network. Only relevant if `add_adapter is + True`. + position_embeddings_type (`str`, *optional*, defaults to `"relative_key"`): + Can be specified to `relative_key`. If left to `None`, no relative position embedding is applied. Only + applied to the speech encoder. For more information on `"relative_key"`, please refer to [Self-Attention + with Relative Position Representations (Shaw et al.)](https://huggingface.co/papers/1803.02155). + conv_depthwise_kernel_size (`int`, *optional*, defaults to 31): + Kernel size of convolutional depthwise 1D layer in Conformer blocks. Only applied to the speech encoder. + left_max_position_embeddings (`int`, *optional*, defaults to 64): + The left clipping value for relative positions. + right_max_position_embeddings (`int`, *optional*, defaults to 8): + The right clipping value for relative positions. + speech_encoder_chunk_size (`int`, *optional*, defaults to 20000): The size of each attention chunk. + speech_encoder_left_chunk_num (`int`, *optional*, defaults to 128): + Number of chunks on the left up to which lookahead is allowed. + + > Text-To-Unit (t2u) model specific parameters + + t2u_bos_token_id (`int`, *optional*, defaults to 0): + The id of the _beginning-of-stream_ unit token. Only applied to the text-to-unit seq2seq model. + t2u_pad_token_id (`int`, *optional*, defaults to 1): + The id of the _padding_ unit token. Only applied to the text-to-unit seq2seq model. + t2u_eos_token_id (`int`, *optional*, defaults to 2): + The id of the _end-of-stream_ unit token. Only applied to the text-to-unit seq2seq model. + t2u_encoder_layers (`int`, *optional*, defaults to 6): + Number of hidden layers in the Transformer text-to-unit encoder. + t2u_encoder_ffn_dim (`int`, *optional*, defaults to 8192): + Dimension of the "intermediate" (i.e., feed-forward) layer in the Transformer text-to-unit encoder. + t2u_encoder_attention_heads (`int`, *optional*, defaults to 16): + Number of attention heads for each attention layer in the Transformer text-to-unit encoder. + t2u_decoder_layers (`int`, *optional*, defaults to 6): + Number of hidden layers in the Transformer text-to-unit decoder. + t2u_decoder_ffn_dim (`int`, *optional*, defaults to 8192): + Dimension of the "intermediate" (i.e., feed-forward) layer in the Transformer text-to-unit decoder. + t2u_decoder_attention_heads (`int`, *optional*, defaults to 16): + Number of attention heads for each attention layer in the Transformer text-to-unit decoder. + t2u_max_position_embeddings (`int`, *optional*, defaults to 4096): + The maximum sequence length that this model text-to-unit component might ever be used with. Typically set + this to something large just in case (e.g., 512 or 1024 or 2048). + t2u_variance_predictor_embed_dim (`int`, *optional*, defaults to 1024): + The projection dimension of the text-to-unit's duration predictor. + t2u_variance_predictor_hidden_dim (`int`, *optional*, defaults to 256): + Internal dimension of the text-to-unit's duration predictor. + t2u_variance_predictor_kernel_size (`int`, *optional*, defaults to 3): + Kernel size of the convolutional layers of the text-to-unit's duration predictor. + t2u_variance_pred_dropout (`float`, *optional*, defaults to 0.5): + The dropout probability of the text-to-unit's duration predictor. + + > Hifi-Gan Vocoder specific parameters + + sampling_rate (`int`, *optional*, defaults to 16000): + The sampling rate at which the output audio will be generated, expressed in hertz (Hz). + upsample_initial_channel (`int`, *optional*, defaults to 512): + The number of input channels into the hifi-gan upsampling network. Applies to the vocoder only. + upsample_rates (`tuple[int]` or `list[int]`, *optional*, defaults to `[5, 4, 4, 2, 2]`): + A tuple of integers defining the stride of each 1D convolutional layer in the vocoder upsampling network. + The length of *upsample_rates* defines the number of convolutional layers and has to match the length of + *upsample_kernel_sizes*. Applies to the vocoder only. + upsample_kernel_sizes (`tuple[int]` or `list[int]`, *optional*, defaults to `[11, 8, 8, 4, 4]`): + A tuple of integers defining the kernel size of each 1D convolutional layer in the vocoder upsampling + network. The length of *upsample_kernel_sizes* defines the number of convolutional layers and has to match + the length of *upsample_rates*. Applies to the vocoder only. + resblock_kernel_sizes (`tuple[int]` or `list[int]`, *optional*, defaults to `[3, 7, 11]`): + A tuple of integers defining the kernel sizes of the vocoder 1D convolutional layers in the multi-receptive + field fusion (MRF) module. Applies to the vocoder only. + resblock_dilation_sizes (`tuple[tuple[int]]` or `list[list[int]]`, *optional*, defaults to `[[1, 3, 5], [1, 3, 5], [1, 3, 5]]`): + A nested tuple of integers defining the dilation rates of the vocoder dilated 1D convolutional layers in + the multi-receptive field fusion (MRF) module. Applies to the vocoder only. + leaky_relu_slope (`float`, *optional*, defaults to 0.1): + The angle of the negative slope used by the leaky ReLU activation in the vocoder. Applies to the vocoder + only. + unit_hifi_gan_vocab_size (`int`, *optional*, defaults to 10000): + Vocabulary size of the SeamlessM4Tv2 vocoder. Defines the number of different unit tokens that can be + represented by the `inputs_ids` passed when calling the vocoder of [`~SeamlessM4Tv2Model`], + [`~SeamlessM4Tv2ForSpeechToSpeech`] or [`~SeamlessM4Tv2ForTextToSpeech`]. + unit_embed_dim (`int`, *optional*, defaults to 1280): + The projection dimension of the input ids given to the hifi-gan vocoder. Applies to the vocoder only. + lang_embed_dim (`int`, *optional*, defaults to 256): + The projection dimension of the target language given to the hifi-gan vocoder. Applies to the vocoder only. + spkr_embed_dim (`int`, *optional*, defaults to 256): + The projection dimension of the speaker id given to the hifi-gan vocoder. Applies to the vocoder only. + vocoder_num_langs (`int`, *optional*, defaults to 36): + Number of langs supported by the vocoder. Might be different from `t2u_num_langs`. + vocoder_num_spkrs (`int`, *optional*, defaults to 200): + Number of speakers supported by the vocoder. + variance_predictor_kernel_size (`int`, *optional*, defaults to 3): + Kernel size of the duration predictor. Applies to the vocoder only. + var_pred_dropout (`float`, *optional*, defaults to 0.5): + The dropout probability of the duration predictor. Applies to the vocoder only. + vocoder_offset (`int`, *optional*, defaults to 4): + Offset the unit token ids by this number to account for symbol tokens. Applies to the vocoder only. + + ```python + >>> from transformers import SeamlessM4Tv2Model, SeamlessM4Tv2Config + + >>> # Initializing a SeamlessM4Tv2 "" style configuration + >>> configuration = SeamlessM4Tv2Config() + + >>> # Initializing a model from the "" style configuration + >>> model = SeamlessM4Tv2Model(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "seamless_m4t_v2" + + def __init__( + self, + vocab_size=256102, + t2u_vocab_size=10082, + char_vocab_size=10943, + # shared config + hidden_size=1024, + initializer_range=0.02, + layer_norm_eps=1e-5, + use_cache=True, + max_position_embeddings=4096, + is_encoder_decoder=True, + encoder_layerdrop=0.05, + decoder_layerdrop=0.05, + activation_function="relu", + dropout=0.1, + attention_dropout=0.1, + activation_dropout=0.0, + scale_embedding=True, + # text encoder|decoder + encoder_layers=24, + encoder_ffn_dim=8192, + encoder_attention_heads=16, + decoder_layers=24, + decoder_ffn_dim=8192, + decoder_attention_heads=16, + decoder_start_token_id=3, + max_new_tokens=256, + pad_token_id=0, + bos_token_id=2, + eos_token_id=3, + # speech_encoder + speech_encoder_layers=24, + speech_encoder_attention_heads=16, + speech_encoder_intermediate_size=4096, + speech_encoder_hidden_act="swish", + speech_encoder_dropout=0.0, + add_adapter=True, + speech_encoder_layerdrop=0.1, + feature_projection_input_dim=160, + adaptor_kernel_size=8, + adaptor_stride=8, + adaptor_dropout=0.1, + num_adapter_layers=1, + position_embeddings_type="relative_key", + conv_depthwise_kernel_size=31, + left_max_position_embeddings=64, + right_max_position_embeddings=8, + speech_encoder_chunk_size=20000, + speech_encoder_left_chunk_num=128, + # t2u config + t2u_bos_token_id=0, + t2u_pad_token_id=1, + t2u_eos_token_id=2, + t2u_encoder_layers=6, + t2u_encoder_ffn_dim=8192, + t2u_encoder_attention_heads=16, + t2u_decoder_layers=6, + t2u_decoder_ffn_dim=8192, + t2u_decoder_attention_heads=16, + t2u_max_position_embeddings=4096, + t2u_variance_predictor_embed_dim=1024, + t2u_variance_predictor_hidden_dim=256, + t2u_variance_predictor_kernel_size=3, + t2u_variance_pred_dropout=0.5, + # hifi-gan vocoder config + sampling_rate=16000, + upsample_initial_channel=512, + upsample_rates=[5, 4, 4, 2, 2], + upsample_kernel_sizes=[11, 8, 8, 4, 4], + resblock_kernel_sizes=[3, 7, 11], + resblock_dilation_sizes=[[1, 3, 5], [1, 3, 5], [1, 3, 5]], + leaky_relu_slope=0.1, + # specific to Code Hifi-Gan + unit_hifi_gan_vocab_size=10000, + unit_embed_dim=1280, + lang_embed_dim=256, + spkr_embed_dim=256, + vocoder_num_langs=36, + vocoder_num_spkrs=200, + variance_predictor_kernel_size=3, + var_pred_dropout=0.5, + vocoder_offset=4, + tie_word_embeddings=True, + **kwargs, + ): + # overall_config + self.vocab_size = vocab_size + self.t2u_vocab_size = t2u_vocab_size + self.char_vocab_size = char_vocab_size + self.hidden_size = hidden_size + self.initializer_range = initializer_range + self.layer_norm_eps = layer_norm_eps + self.max_position_embeddings = max_position_embeddings + self.use_cache = use_cache + self.max_new_tokens = max_new_tokens + self.encoder_layerdrop = encoder_layerdrop + self.decoder_layerdrop = decoder_layerdrop + self.activation_function = activation_function + self.dropout = dropout + self.attention_dropout = attention_dropout + self.activation_dropout = activation_dropout + self.scale_embedding = scale_embedding + self.tie_word_embeddings = tie_word_embeddings + # for proper config init + self.num_attention_heads = decoder_attention_heads + self.num_hidden_layers = decoder_layers + + # text|unit encoder|decoder + self.encoder_layers = encoder_layers + self.encoder_ffn_dim = encoder_ffn_dim + self.encoder_attention_heads = encoder_attention_heads + self.decoder_layers = decoder_layers + self.decoder_ffn_dim = decoder_ffn_dim + self.decoder_attention_heads = decoder_attention_heads + + # speech_encoder + self.speech_encoder_layers = speech_encoder_layers + self.speech_encoder_hidden_act = speech_encoder_hidden_act + self.speech_encoder_dropout = speech_encoder_dropout + self.speech_encoder_attention_heads = speech_encoder_attention_heads + self.speech_encoder_layerdrop = speech_encoder_layerdrop + self.speech_encoder_intermediate_size = speech_encoder_intermediate_size + self.feature_projection_input_dim = feature_projection_input_dim + self.adaptor_kernel_size = adaptor_kernel_size + self.adaptor_stride = adaptor_stride + self.adaptor_dropout = adaptor_dropout + self.num_adapter_layers = num_adapter_layers + self.position_embeddings_type = position_embeddings_type + self.conv_depthwise_kernel_size = conv_depthwise_kernel_size + self.add_adapter = add_adapter + self.left_max_position_embeddings = left_max_position_embeddings + self.right_max_position_embeddings = right_max_position_embeddings + self.speech_encoder_chunk_size = speech_encoder_chunk_size + self.speech_encoder_left_chunk_num = speech_encoder_left_chunk_num + + # t2u config + self.t2u_bos_token_id = t2u_bos_token_id + self.t2u_pad_token_id = t2u_pad_token_id + self.t2u_eos_token_id = t2u_eos_token_id + self.t2u_encoder_layers = t2u_encoder_layers + self.t2u_encoder_ffn_dim = t2u_encoder_ffn_dim + self.t2u_encoder_attention_heads = t2u_encoder_attention_heads + self.t2u_decoder_layers = t2u_decoder_layers + self.t2u_decoder_ffn_dim = t2u_decoder_ffn_dim + self.t2u_decoder_attention_heads = t2u_decoder_attention_heads + self.t2u_max_position_embeddings = t2u_max_position_embeddings + self.t2u_variance_predictor_embed_dim = t2u_variance_predictor_embed_dim # TODO: add to docstrings + self.t2u_variance_predictor_hidden_dim = t2u_variance_predictor_hidden_dim # TODO: add to docstrings + self.t2u_variance_predictor_kernel_size = t2u_variance_predictor_kernel_size # TODO: add to docstrings + self.t2u_variance_pred_dropout = t2u_variance_pred_dropout # TODO: add to docstrings + + # hifi-gan vocoder config + # original parameters specific to Hifi-Gan + self.sampling_rate = sampling_rate + self.upsample_initial_channel = upsample_initial_channel + self.upsample_rates = upsample_rates + self.upsample_kernel_sizes = upsample_kernel_sizes + self.resblock_kernel_sizes = resblock_kernel_sizes + self.resblock_dilation_sizes = resblock_dilation_sizes + self.leaky_relu_slope = leaky_relu_slope + + # specific to Code Hifi-Gan + self.unit_hifi_gan_vocab_size = unit_hifi_gan_vocab_size + self.unit_embed_dim = unit_embed_dim + self.lang_embed_dim = lang_embed_dim + self.spkr_embed_dim = spkr_embed_dim + self.vocoder_num_langs = vocoder_num_langs + self.vocoder_num_spkrs = vocoder_num_spkrs + self.variance_predictor_kernel_size = variance_predictor_kernel_size + self.var_pred_dropout = var_pred_dropout + self.vocoder_offset = vocoder_offset + self.pad_token_id = pad_token_id + self.bos_token_id = bos_token_id + self.eos_token_id = eos_token_id + self.decoder_start_token_id = decoder_start_token_id + self.max_position_embeddings = max_position_embeddings + + super().__init__(is_encoder_decoder=is_encoder_decoder, **kwargs) + + +__all__ = ["SeamlessM4Tv2Config"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/seamless_m4t_v2/modeling_seamless_m4t_v2.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/seamless_m4t_v2/modeling_seamless_m4t_v2.py new file mode 100644 index 0000000000000000000000000000000000000000..cb4113da7326f43a4403583128ab921be4dc1193 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/seamless_m4t_v2/modeling_seamless_m4t_v2.py @@ -0,0 +1,4372 @@ +# Copyright 2023 The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""PyTorch SeamlessM4Tv2 model.""" + +import copy +import math +from dataclasses import dataclass + +import torch +from torch import Tensor, nn +from torch.nn import CrossEntropyLoss + +from ... import initialization as init +from ...activations import ACT2FN +from ...cache_utils import Cache, DynamicCache, EncoderDecoderCache +from ...generation import GenerationMixin +from ...integrations.deepspeed import is_deepspeed_zero3_enabled +from ...integrations.fsdp import is_fsdp_managed_module +from ...masking_utils import create_bidirectional_mask, create_causal_mask +from ...modeling_layers import GradientCheckpointingLayer +from ...modeling_outputs import ( + BaseModelOutput, + BaseModelOutputWithPastAndCrossAttentions, + Seq2SeqLMOutput, + Seq2SeqModelOutput, + Wav2Vec2BaseModelOutput, +) +from ...modeling_utils import PreTrainedModel +from ...utils import ModelOutput, auto_docstring, logging +from ...utils.deprecation import deprecate_kwarg +from .configuration_seamless_m4t_v2 import SeamlessM4Tv2Config + + +logger = logging.get_logger(__name__) + +SEAMLESS_M4T_V2_COMMON_CUSTOM_ARGS = r""" + input_features (`torch.FloatTensor` of shape `(batch_size, sequence_length, num_banks)`): + Input audio features. This should be returned by the [`SeamlessM4TFeatureExtractor`] class or the + [`SeamlessM4TProcessor`] class. See [`SeamlessM4TFeatureExtractor.__call__`] for details. + decoder_input_ids (`torch.LongTensor` of shape `(batch_size, target_sequence_length)`, *optional*): + Indices of decoder input sequence tokens in the vocabulary. + + Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and + [`PreTrainedTokenizer.__call__`] for details. + + [What are decoder input IDs?](../glossary#decoder-input-ids) + + Bart uses the `eos_token_id` as the starting token for `decoder_input_ids` generation. If `past_key_values` + is used, optionally only the last `decoder_input_ids` have to be input (see `past_key_values`). + + For translation and summarization training, `decoder_input_ids` should be provided. If no + `decoder_input_ids` is provided, the model will create this tensor by shifting the `input_ids` to the right + for denoising pre-training following the paper. + decoder_attention_mask (`torch.LongTensor` of shape `(batch_size, target_sequence_length)`, *optional*): + Default behavior: generate a tensor that ignores pad tokens in `decoder_input_ids`. Causal mask will also + be used by default. + + If you want to change padding behavior, you should read [`modeling_bart._prepare_decoder_attention_mask`] + and modify to your needs. See diagram 1 in [the paper](https://huggingface.co/papers/1910.13461) for more + information on the default strategy. + inputs_embeds (`torch.FloatTensor` of shape`(batch_size, sequence_length, hidden_size)`, *optional*): + Optionally, instead of passing `input_ids` you can choose to directly pass an embedded representation. This + is useful if you want more control over how to convert `input_ids` indices into associated vectors than the + model's internal embedding lookup matrix. +""" + + +@dataclass +@auto_docstring( + custom_intro=""" + Class defining the generated outputs from [`SeamlessM4Tv2Model`], [`SeamlessM4Tv2ForTextToText`], + [`SeamlessM4Tv2ForTextToSpeech`], [`SeamlessM4Tv2ForSpeechToSpeech`] and [`SeamlessM4Tv2ForTextToSpeech`]. + """ +) +# Copied from transformers.models.seamless_m4t.modeling_seamless_m4t.SeamlessM4TGenerationOutput with SeamlessM4T->SeamlessM4Tv2 +class SeamlessM4Tv2GenerationOutput(ModelOutput): + r""" + waveform (`torch.FloatTensor` of shape `(batch_size, sequence_length)`): + The final audio waveform predicted by the model. + waveform_lengths (`torch.IntTensor` of shape `(batch_size,)`, *optional*): + The length in samples of each element in the `waveform` batch. + sequences (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + The generated translated sequences. This is the output of the text-to-text or the speech-to-text models. + The second dimension (sequence_length) is either equal to `max_length` or shorter if all batches finished + early due to the `eos_token_id`. + unit_sequences (`torch.LongTensor` of shape `(batch_size, unit_sequence_length)`, *optional*): + The generated translated unit sequences. This is the output of the text-to-units model. The second + dimension (unit_sequence_length) is either equal to `t2u_max_length` or shorter if all batches finished + early due to the `t2u_eos_token_id`. + """ + + waveform: torch.FloatTensor | None = None + waveform_lengths: torch.IntTensor | None = None + sequences: tuple[torch.FloatTensor] | None = None + unit_sequences: tuple[torch.FloatTensor] | None = None + + +@dataclass +@auto_docstring( + custom_intro=""" + Class defining the outputs from [`SeamlessM4Tv2TextToUnitDecoder`]. + """ +) +class SeamlessM4Tv2TextToUnitDecoderOutput(ModelOutput): + r""" + padding_mask (`torch.Tensor` of shape `(batch_size, sequence_length)`, *optional*): + Indicates which inputs are to be ignored due to padding, where elements are either 1 for *not masked* or 0 + for *masked* + """ + + last_hidden_state: torch.FloatTensor | None = None + hidden_states: tuple[torch.FloatTensor] | None = None + attentions: tuple[torch.FloatTensor] | None = None + padding_mask: torch.Tensor | None = None + + +@dataclass +@auto_docstring( + custom_intro=""" + Class defining the outputs from [`SeamlessM4Tv2TextToUnitForConditionalGeneration`] and + [`SeamlessM4Tv2TextToUnitModel`]. + """ +) +class SeamlessM4Tv2TextToUnitOutput(ModelOutput): + r""" + last_hidden_state (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`): + Sequence of hidden-states at the output of the last layer of the decoder of the model. + + If `past_key_values` is used only the last hidden-state of the sequences of shape `(batch_size, 1, + hidden_size)` is output. + padding_mask (`torch.Tensor` of shape `(batch_size, sequence_length)`, *optional*): + Indicates which inputs are to be ignored due to padding, where elements are either 1 for *not masked* or 0 + for *masked* + loss (`torch.FloatTensor` of shape `(1,)`, *optional*, returned when `labels` is provided): + Language modeling loss. + """ + + last_hidden_state: torch.FloatTensor | None = None + padding_mask: torch.Tensor | None = None + decoder_hidden_states: tuple[torch.FloatTensor] | None = None + decoder_attentions: tuple[torch.FloatTensor] | None = None + encoder_last_hidden_state: torch.FloatTensor | None = None + encoder_hidden_states: tuple[torch.FloatTensor] | None = None + encoder_attentions: tuple[torch.FloatTensor] | None = None + loss: torch.FloatTensor | None = None + + +############ UTILS ################ + + +# Copied from transformers.models.bart.modeling_bart.shift_tokens_right +def shift_tokens_right(input_ids: torch.Tensor, pad_token_id: int, decoder_start_token_id: int): + """ + Shift input ids one token to the right. + """ + shifted_input_ids = input_ids.new_zeros(input_ids.shape) + shifted_input_ids[:, 1:] = input_ids[:, :-1].clone() + shifted_input_ids[:, 0] = decoder_start_token_id + + if pad_token_id is None: + raise ValueError("self.model.config.pad_token_id has to be defined.") + # replace possible -100 values in labels by `pad_token_id` + shifted_input_ids.masked_fill_(shifted_input_ids == -100, pad_token_id) + + return shifted_input_ids + + +def _compute_new_attention_mask(hidden_states: torch.Tensor, seq_lens: torch.Tensor): + """ + Computes an attention mask of the form `(batch, seq_len)` with an attention for each element in the batch that + stops at the corresponding element in `seq_lens`. + + Args: + hidden_states (`torch.FloatTensor` of shape `(batch, seq_len, *)`): + The sequences to mask, where `*` is any number of sequence-specific dimensions including none. + seq_lens (`torch.Tensor` of shape `(batch)`: + Each element represents the length of the sequence at the same index in `hidden_states` + + Returns: + `torch.FloatTensor`: The float attention mask of shape `(batch, seq_len)` + """ + batch_size, mask_seq_len = hidden_states.shape[:2] + + indices = torch.arange(mask_seq_len, device=seq_lens.device).expand(batch_size, -1) + + bool_mask = indices >= seq_lens.unsqueeze(1).expand(-1, mask_seq_len) + + mask = hidden_states.new_ones((batch_size, mask_seq_len)) + + mask = mask.masked_fill(bool_mask, 0) + + return mask + + +# Copied from transformers.models.seamless_m4t.modeling_seamless_m4t.format_speech_generation_kwargs with SeamlessM4T->SeamlessM4Tv2 +def format_speech_generation_kwargs(kwargs): + """ + Format kwargs for SeamlessM4Tv2 models that generate speech, attribute kwargs to either the text generation or the + speech generation models. + + Args: + kwargs (`dict`)`: + Keyword arguments are of two types: + + - Without a prefix, they will be entered as `**kwargs` for the `generate` method of each sub-model, + except for `decoder_input_ids` which will only be passed through the text components. + - With a *text_* or *speech_* prefix, they will be input for the `generate` method of the + text model and speech model respectively. It has the priority over the keywords without a prefix. + + This means you can, for example, specify a generation strategy for one generation but not for the + other. + """ + # attribute kwargs to models + kwargs_text = {} + kwargs_speech = {} + for key, value in kwargs.items(): + if key.startswith("text_"): + key = key[len("text_") :] + kwargs_text[key] = value + elif key.startswith("speech_"): + key = key[len("speech_") :] + kwargs_speech[key] = value + elif key == "generation_config": + kwargs_text[key] = value + else: + # If the key is already in a specific config, then it's been set with a + # submodules specific value and we don't override + if key not in kwargs_text: + kwargs_text[key] = value + if key not in kwargs_speech: + kwargs_speech[key] = value + return kwargs_text, kwargs_speech + + +############ SPEECH ENCODER related code ################ + + +class SeamlessM4Tv2ConformerFeatureProjection(nn.Module): + # Copied from transformers.models.seamless_m4t.modeling_seamless_m4t.SeamlessM4TConformerFeatureProjection.__init__ + def __init__(self, config): + super().__init__() + self.layer_norm = nn.LayerNorm(config.feature_projection_input_dim, eps=config.layer_norm_eps) + self.projection = nn.Linear(config.feature_projection_input_dim, config.hidden_size) + self.dropout = nn.Dropout(config.speech_encoder_dropout) + + def forward(self, hidden_states): + # non-projected hidden states are needed for quantization + norm_hidden_states = self.layer_norm(hidden_states.to(self.layer_norm.weight.dtype)) + hidden_states = self.projection(norm_hidden_states) + hidden_states = self.dropout(hidden_states) + return hidden_states + + +# Copied from transformers.models.seamless_m4t.modeling_seamless_m4t.SeamlessM4TConformerFeedForward with SeamlessM4T->SeamlessM4Tv2 +class SeamlessM4Tv2ConformerFeedForward(nn.Module): + def __init__(self, config, act_fn=None, dropout=None): + super().__init__() + dropout = dropout if dropout is not None else config.speech_encoder_dropout + act_fn = act_fn if act_fn is not None else config.speech_encoder_hidden_act + + self.intermediate_dropout = nn.Dropout(dropout) + self.intermediate_dense = nn.Linear(config.hidden_size, config.speech_encoder_intermediate_size) + self.intermediate_act_fn = ACT2FN[act_fn] if isinstance(act_fn, str) else act_fn + + self.output_dense = nn.Linear(config.speech_encoder_intermediate_size, config.hidden_size) + self.output_dropout = nn.Dropout(dropout) + + def forward(self, hidden_states): + hidden_states = self.intermediate_dense(hidden_states) + hidden_states = self.intermediate_act_fn(hidden_states) + hidden_states = self.intermediate_dropout(hidden_states) + + hidden_states = self.output_dense(hidden_states) + hidden_states = self.output_dropout(hidden_states) + return hidden_states + + +class SeamlessM4Tv2ConformerConvolutionModule(nn.Module): + """Convolution block used in the conformer block. Uses a causal depthwise convolution similar to that + described in Section 2.1 of https://huggingface.co/papers/1609.03499 + """ + + def __init__(self, config): + super().__init__() + if (config.conv_depthwise_kernel_size - 1) % 2 == 1: + raise ValueError("`config.conv_depthwise_kernel_size` should be a odd number for 'SAME' padding") + self.layer_norm = nn.LayerNorm(config.hidden_size) + self.pointwise_conv1 = nn.Conv1d( + config.hidden_size, + 2 * config.hidden_size, + kernel_size=1, + stride=1, + padding=0, + bias=False, + ) + self.glu = nn.GLU(dim=1) + self.depthwise_conv = nn.Conv1d( + config.hidden_size, + config.hidden_size, + config.conv_depthwise_kernel_size, + stride=1, + padding=0, + groups=config.hidden_size, + bias=False, + ) + self.depthwise_layer_norm = nn.LayerNorm(config.hidden_size) + self.activation = ACT2FN[config.speech_encoder_hidden_act] + self.pointwise_conv2 = nn.Conv1d( + config.hidden_size, + config.hidden_size, + kernel_size=1, + stride=1, + padding=0, + bias=False, + ) + self.dropout = nn.Dropout(config.speech_encoder_dropout) + + def forward(self, hidden_states, attention_mask=None): + hidden_states = self.layer_norm(hidden_states) + + # Ensure that we do not leak padded positions in depthwise convolution. + # Put 0 where necessary + if attention_mask is not None: + hidden_states = hidden_states.masked_fill(~attention_mask.bool().unsqueeze(-1), 0.0) + + # exchange the temporal dimension and the feature dimension + hidden_states = hidden_states.transpose(1, 2) + + # GLU mechanism + # => (batch, 2*channel, dim) + hidden_states = self.pointwise_conv1(hidden_states) + # => (batch, channel, dim) + hidden_states = self.glu(hidden_states) + + # Pad the sequence entirely on the left because of causal convolution. + hidden_states = torch.nn.functional.pad(hidden_states, (self.depthwise_conv.kernel_size[0] - 1, 0)) + + # 1D Depthwise Conv + hidden_states = self.depthwise_conv(hidden_states) + hidden_states = self.depthwise_layer_norm(hidden_states.transpose(1, 2)).transpose(1, 2) + hidden_states = self.activation(hidden_states) + + hidden_states = self.pointwise_conv2(hidden_states) + hidden_states = self.dropout(hidden_states) + hidden_states = hidden_states.transpose(1, 2) + return hidden_states + + +class SeamlessM4Tv2ConformerSelfAttention(nn.Module): + """Construct a SeamlessM4Tv2ConformerSelfAttention object. + Can be enhanced with relative position embeddings. + """ + + def __init__(self, config, use_position_embeddings=True): + super().__init__() + + self.head_size = config.hidden_size // config.speech_encoder_attention_heads + self.num_heads = config.speech_encoder_attention_heads + self.position_embeddings_type = config.position_embeddings_type if use_position_embeddings else None + + self.linear_q = nn.Linear(config.hidden_size, config.hidden_size) + self.linear_k = nn.Linear(config.hidden_size, config.hidden_size) + self.linear_v = nn.Linear(config.hidden_size, config.hidden_size) + self.linear_out = nn.Linear(config.hidden_size, config.hidden_size) + + self.dropout = nn.Dropout(p=config.speech_encoder_dropout) + + if self.position_embeddings_type == "relative_key": + self.left_max_position_embeddings = config.left_max_position_embeddings + self.right_max_position_embeddings = config.right_max_position_embeddings + num_positions = self.left_max_position_embeddings + self.right_max_position_embeddings + 1 + self.distance_embedding = nn.Embedding(num_positions, self.head_size) + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.Tensor | None = None, + output_attentions: bool = False, + ) -> tuple[torch.Tensor, torch.Tensor | None, tuple[torch.Tensor] | None]: + # self-attention mechanism + batch_size, sequence_length, hidden_size = hidden_states.size() + + # make sure query/key states can be != value states + query_key_states = hidden_states + value_states = hidden_states + + # project query_key_states and value_states + query = self.linear_q(query_key_states).view(batch_size, -1, self.num_heads, self.head_size) + key = self.linear_k(query_key_states).view(batch_size, -1, self.num_heads, self.head_size) + value = self.linear_v(value_states).view(batch_size, -1, self.num_heads, self.head_size) + + # => (batch, head, time1, d_k) + query = query.transpose(1, 2) + key = key.transpose(1, 2) + value = value.transpose(1, 2) + + attn_weights = torch.matmul(query, key.transpose(-2, -1)) / math.sqrt(self.head_size) + + if self.position_embeddings_type == "relative_key": + query_length, key_length = query.shape[2], key.shape[2] + + position_ids_l = torch.arange(query_length, dtype=torch.long, device=hidden_states.device).view(-1, 1) + position_ids_r = torch.arange(key_length, dtype=torch.long, device=hidden_states.device).view(1, -1) + distance = position_ids_r - position_ids_l + distance = torch.clamp(distance, -self.left_max_position_embeddings, self.right_max_position_embeddings) + + positional_embedding = self.distance_embedding(distance + self.left_max_position_embeddings) + positional_embedding = positional_embedding.to(dtype=query.dtype) # fp16 compatibility + + relative_position_attn_weights = torch.einsum("bhld,lrd->bhlr", query, positional_embedding) + attn_weights = attn_weights + (relative_position_attn_weights / math.sqrt(self.head_size)) + + # apply attention_mask if necessary + if attention_mask is not None: + attn_weights = attn_weights + attention_mask + + # => (batch, head, time1, time2) + attn_weights = torch.softmax(attn_weights, dim=-1) + attn_weights = self.dropout(attn_weights) + + # => (batch, head, time1, d_k) + attn_output = torch.matmul(attn_weights, value) + + # => (batch, time1, hidden_size) + attn_output = attn_output.transpose(1, 2).reshape(batch_size, -1, self.num_heads * self.head_size) + attn_output = self.linear_out(attn_output) + + if not output_attentions: + attn_weights = None + + return attn_output, attn_weights + + +class SeamlessM4Tv2ConformerEncoderLayer(GradientCheckpointingLayer): + """Conformer block based on https://huggingface.co/papers/2005.08100.""" + + # Copied from transformers.models.wav2vec2_conformer.modeling_wav2vec2_conformer.Wav2Vec2ConformerEncoderLayer.__init__ with Wav2Vec2->SeamlessM4Tv2, attention_dropout->speech_encoder_dropout, torch.nn->nn + def __init__(self, config): + super().__init__() + embed_dim = config.hidden_size + dropout = config.speech_encoder_dropout + + # Feed-forward 1 + self.ffn1_layer_norm = nn.LayerNorm(embed_dim) + self.ffn1 = SeamlessM4Tv2ConformerFeedForward(config) + + # Self-Attention + self.self_attn_layer_norm = nn.LayerNorm(embed_dim) + self.self_attn_dropout = nn.Dropout(dropout) + self.self_attn = SeamlessM4Tv2ConformerSelfAttention(config) + + # Conformer Convolution + self.conv_module = SeamlessM4Tv2ConformerConvolutionModule(config) + + # Feed-forward 2 + self.ffn2_layer_norm = nn.LayerNorm(embed_dim) + self.ffn2 = SeamlessM4Tv2ConformerFeedForward(config) + self.final_layer_norm = nn.LayerNorm(embed_dim) + + def forward( + self, + hidden_states, + attention_mask: torch.Tensor | None = None, + output_attentions: bool = False, + conv_attention_mask: torch.Tensor | None = None, + ): + # 1. Feed-Forward 1 layer + residual = hidden_states + hidden_states = self.ffn1_layer_norm(hidden_states) + hidden_states = self.ffn1(hidden_states) + hidden_states = hidden_states * 0.5 + residual + residual = hidden_states + + # 2. Self-Attention layer + hidden_states = self.self_attn_layer_norm(hidden_states) + hidden_states, attn_weights = self.self_attn( + hidden_states=hidden_states, + attention_mask=attention_mask, + output_attentions=output_attentions, + ) + hidden_states = self.self_attn_dropout(hidden_states) + hidden_states = hidden_states + residual + + # 3. Convolutional Layer + residual = hidden_states + hidden_states = self.conv_module(hidden_states, attention_mask=conv_attention_mask) + hidden_states = residual + hidden_states + + # 4. Feed-Forward 2 Layer + residual = hidden_states + hidden_states = self.ffn2_layer_norm(hidden_states) + hidden_states = self.ffn2(hidden_states) + hidden_states = hidden_states * 0.5 + residual + hidden_states = self.final_layer_norm(hidden_states) + + return hidden_states, attn_weights + + +class SeamlessM4Tv2ConformerEncoder(nn.Module): + def __init__(self, config): + super().__init__() + self.config = config + + self.dropout = nn.Dropout(config.speech_encoder_dropout) + self.layers = nn.ModuleList( + [SeamlessM4Tv2ConformerEncoderLayer(config) for _ in range(config.speech_encoder_layers)] + ) + + self.layer_norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps) + + self.gradient_checkpointing = False + + def _apply_chunk_attention(self, attention_mask, hidden_states): + """ + Creates a chunk attention mask. It creates a mask to prevent attention across chunks, ensuring that each + position attends only to positions within its own chunk. If a left chunk overlap is specified + (`speech_encoder_chunk_size` in the configuration), the attention mask is adjusted accordingly to allow each + position to also attends the `speech_encoder_chunk_size - 1` previous chunks. + """ + sequence_len = hidden_states.shape[1] + + chunk_indices = torch.arange(sequence_len, device=hidden_states.device) + chunk_indices = torch.div(chunk_indices, self.config.speech_encoder_chunk_size).long() + + start_indices = torch.full_like(chunk_indices, 0) + if self.config.speech_encoder_left_chunk_num >= 0: + start_indices = (chunk_indices - self.config.speech_encoder_left_chunk_num).clamp_(min=0) + start_indices = start_indices * self.config.speech_encoder_chunk_size + start_indices = start_indices.unsqueeze(1).expand(-1, sequence_len) + + end_indices = ((chunk_indices + 1) * self.config.speech_encoder_chunk_size).clamp_(max=sequence_len) + + end_indices = end_indices.unsqueeze(1).expand(-1, sequence_len) + + indices = torch.arange(sequence_len, device=hidden_states.device).unsqueeze(0).expand(sequence_len, -1) + + chunk_mask = (indices < start_indices) | (indices >= end_indices) + chunk_mask = chunk_mask.unsqueeze(0).unsqueeze(0) + + attention_mask = chunk_mask if attention_mask is None else (attention_mask.bool() | chunk_mask) + attention_mask = attention_mask.to(dtype=hidden_states.dtype) + return attention_mask + + def forward( + self, + hidden_states, + attention_mask=None, + output_attentions=False, + output_hidden_states=False, + return_dict=True, + ): + all_hidden_states = () if output_hidden_states else None + all_self_attentions = () if output_attentions else None + + conv_attention_mask = attention_mask + if attention_mask is not None: + # make sure padded tokens output 0 + hidden_states = hidden_states.masked_fill(~attention_mask.bool().unsqueeze(-1), 0.0) + # extend attention_mask + attention_mask = 1.0 - attention_mask[:, None, None, :].to(dtype=hidden_states.dtype) + attention_mask = attention_mask.expand( + attention_mask.shape[0], 1, attention_mask.shape[-1], attention_mask.shape[-1] + ) + + if self.config.speech_encoder_chunk_size is not None: + attention_mask = self._apply_chunk_attention(attention_mask, hidden_states) + + if attention_mask is not None: + attention_mask = attention_mask * torch.finfo(hidden_states.dtype).min + + hidden_states = self.dropout(hidden_states) + + synced_gpus = is_deepspeed_zero3_enabled() or is_fsdp_managed_module(self) + + for i, layer in enumerate(self.layers): + if output_hidden_states: + all_hidden_states = all_hidden_states + (hidden_states,) + + # add LayerDrop (see https://huggingface.co/papers/1909.11556 for description) + dropout_probability = torch.rand([]) + + skip_the_layer = self.training and dropout_probability < self.config.speech_encoder_layerdrop + if not skip_the_layer or synced_gpus: + # under fsdp or deepspeed zero3 all gpus must run in sync + layer_outputs = layer( + hidden_states, + attention_mask=attention_mask, + output_attentions=output_attentions, + conv_attention_mask=conv_attention_mask, + ) + hidden_states = layer_outputs[0] + + if skip_the_layer: + layer_outputs = (None, None) + + if output_attentions: + all_self_attentions = all_self_attentions + (layer_outputs[1],) + + hidden_states = self.layer_norm(hidden_states) + if output_hidden_states: + all_hidden_states = all_hidden_states + (hidden_states,) + + if not return_dict: + return tuple(v for v in [hidden_states, all_hidden_states, all_self_attentions] if v is not None) + return BaseModelOutput( + last_hidden_state=hidden_states, + hidden_states=all_hidden_states, + attentions=all_self_attentions, + ) + + +# Copied from transformers.models.seamless_m4t.modeling_seamless_m4t.SeamlessM4TConformerAdapterLayer with SeamlessM4T->SeamlessM4Tv2 +class SeamlessM4Tv2ConformerAdapterLayer(nn.Module): + def __init__(self, config): + super().__init__() + self.config = config + + embed_dim = config.hidden_size + dropout = config.adaptor_dropout + + self.kernel_size = config.adaptor_kernel_size + self.stride = config.adaptor_stride + + # 1. residual convolution + self.residual_layer_norm = nn.LayerNorm(embed_dim) + self.residual_conv = nn.Conv1d( + embed_dim, + 2 * embed_dim, + self.kernel_size, + stride=self.stride, + padding=self.stride // 2, + ) + self.activation = nn.GLU(dim=1) + + # Self-Attention + self.self_attn_layer_norm = nn.LayerNorm(embed_dim) + self.self_attn_conv = nn.Conv1d( + embed_dim, + 2 * embed_dim, + self.kernel_size, + stride=self.stride, + padding=self.stride // 2, + ) + self.self_attn = SeamlessM4Tv2ConformerSelfAttention(config, use_position_embeddings=False) + self.self_attn_dropout = nn.Dropout(dropout) + + # Feed-forward + self.ffn_layer_norm = nn.LayerNorm(embed_dim) + self.ffn = SeamlessM4Tv2ConformerFeedForward(config, act_fn="relu", dropout=dropout) + + def _compute_sub_sample_lengths_from_attention_mask(self, attention_mask): + pad = self.kernel_size // 2 + seq_lens = attention_mask.size(1) - (1 - attention_mask.int()).sum(1) + + seq_lens = ((seq_lens + 2 * pad - self.kernel_size) / self.stride) + 1 + + return seq_lens.floor() + + def forward( + self, + hidden_states, + attention_mask: torch.Tensor | None = None, + output_attentions: bool = False, + ): + residual = self.residual_layer_norm(hidden_states) + + # Apply pooling to the residual to match the sequence length of the + # multi-head attention output. + # (batch, seq_len, feature_dim) -> (batch, feature_dim, seq_len) + residual = residual.transpose(1, 2) + residual = self.residual_conv(residual) + residual = self.activation(residual) + # (batch, feature_dim, seq_len) -> (batch, seq_len, feature_dim) + residual = residual.transpose(1, 2) + + hidden_states = self.self_attn_layer_norm(hidden_states) + # Apply pooling before feeding to the multihead-attention layer. + # (batch, seq_len, feature_dim) -> (batch, feature_dim, seq_len) + hidden_states = hidden_states.transpose(1, 2) + hidden_states = self.self_attn_conv(hidden_states) + hidden_states = self.activation(hidden_states) + # (batch, feature_dim, seq_len) -> (batch, seq_len, feature_dim) + hidden_states = hidden_states.transpose(1, 2) + + if attention_mask is not None: + sub_sampled_lengths = self._compute_sub_sample_lengths_from_attention_mask(attention_mask).to( + hidden_states.device + ) + attention_mask = _compute_new_attention_mask(hidden_states=hidden_states, seq_lens=sub_sampled_lengths) + attention_mask = create_bidirectional_mask( + config=self.config, + inputs_embeds=hidden_states, + attention_mask=attention_mask, + ) + + # The rest of the computation is identical to a vanilla Transformer + # encoder layer. + hidden_states, attn_weights = self.self_attn( + hidden_states, + attention_mask=attention_mask, + output_attentions=output_attentions, + ) + hidden_states = self.self_attn_dropout(hidden_states) + hidden_states = hidden_states + residual + + residual = hidden_states + + hidden_states = self.ffn_layer_norm(hidden_states) + hidden_states = self.ffn(hidden_states) + residual + + return hidden_states + + +# Copied from transformers.models.seamless_m4t.modeling_seamless_m4t.SeamlessM4TConformerAdapter with SeamlessM4T->SeamlessM4Tv2 +class SeamlessM4Tv2ConformerAdapter(nn.Module): + def __init__(self, config): + super().__init__() + + self.layers = nn.ModuleList( + SeamlessM4Tv2ConformerAdapterLayer(config) for _ in range(config.num_adapter_layers) + ) + + def forward(self, hidden_states, attention_mask): + # down project hidden_states if necessary + + for layer in self.layers: + hidden_states = layer(hidden_states, attention_mask) + + return hidden_states + + +############ TEXT / UNITS related code ################ + + +# Copied from transformers.models.m2m_100.modeling_m2m_100.M2M100ScaledWordEmbedding with M2M100->SeamlessM4Tv2 +class SeamlessM4Tv2ScaledWordEmbedding(nn.Embedding): + """ + This module overrides nn.Embeddings' forward by multiplying with embeddings scale. + """ + + def __init__(self, num_embeddings: int, embedding_dim: int, padding_idx: int, embed_scale: float | None = 1.0): + super().__init__(num_embeddings, embedding_dim, padding_idx) + self.embed_scale = embed_scale + + def forward(self, input_ids: torch.Tensor): + return super().forward(input_ids) * self.embed_scale + + +# Copied from transformers.models.m2m_100.modeling_m2m_100.M2M100SinusoidalPositionalEmbedding with M2M100->SeamlessM4Tv2 +class SeamlessM4Tv2SinusoidalPositionalEmbedding(nn.Module): + """This module produces sinusoidal positional embeddings of any length.""" + + def __init__(self, num_positions: int, embedding_dim: int, padding_idx: int | None = None): + super().__init__() + self.offset = 2 + self.num_positions = num_positions + self.embedding_dim = embedding_dim + self.padding_idx = padding_idx + self.make_weights(num_positions + self.offset, embedding_dim, padding_idx) + + def make_weights(self, num_embeddings: int, embedding_dim: int, padding_idx: int | None = None): + emb_weights = self.get_embedding(num_embeddings, embedding_dim, padding_idx) + if hasattr(self, "weights"): + # in forward put the weights on the correct dtype and device of the param + emb_weights = emb_weights.to(dtype=self.weights.dtype, device=self.weights.device) + + self.register_buffer("weights", emb_weights, persistent=False) + + @staticmethod + def get_embedding(num_embeddings: int, embedding_dim: int, padding_idx: int | None = None): + """ + Build sinusoidal embeddings. + + This matches the implementation in tensor2tensor, but differs slightly from the description in Section 3.5 of + "Attention Is All You Need". + """ + half_dim = embedding_dim // 2 + emb = math.log(10000) / (half_dim - 1) + emb = torch.exp(torch.arange(half_dim, dtype=torch.int64).float() * -emb) + emb = torch.arange(num_embeddings, dtype=torch.int64).float().unsqueeze(1) * emb.unsqueeze(0) + emb = torch.cat([torch.sin(emb), torch.cos(emb)], dim=1).view(num_embeddings, -1) + if embedding_dim % 2 == 1: + # zero pad + emb = torch.cat([emb, torch.zeros(num_embeddings, 1)], dim=1) + if padding_idx is not None: + emb[padding_idx, :] = 0 + + return emb.to(torch.get_default_dtype()) + + @torch.no_grad() + def forward( + self, + input_ids: torch.Tensor | None = None, + inputs_embeds: torch.Tensor | None = None, + past_key_values_length: int = 0, + ): + if input_ids is not None: + bsz, seq_len = input_ids.size() + # Create the position ids from the input token ids. Any padded tokens remain padded. + position_ids = self.create_position_ids_from_input_ids( + input_ids, self.padding_idx, past_key_values_length + ).to(input_ids.device) + else: + bsz, seq_len = inputs_embeds.size()[:-1] + position_ids = self.create_position_ids_from_inputs_embeds( + inputs_embeds, past_key_values_length, self.padding_idx + ) + + # expand embeddings if needed + max_pos = self.padding_idx + 1 + seq_len + past_key_values_length + if max_pos > self.weights.size(0): + self.make_weights(max_pos + self.offset, self.embedding_dim, self.padding_idx) + + return self.weights.index_select(0, position_ids.view(-1)).view(bsz, seq_len, self.weights.shape[-1]).detach() + + @staticmethod + def create_position_ids_from_inputs_embeds(inputs_embeds, past_key_values_length, padding_idx): + """ + We are provided embeddings directly. We cannot infer which are padded so just generate sequential position ids. + + Args: + inputs_embeds: torch.Tensor + + Returns: torch.Tensor + """ + input_shape = inputs_embeds.size()[:-1] + sequence_length = input_shape[1] + + position_ids = torch.arange( + padding_idx + 1, sequence_length + padding_idx + 1, dtype=torch.long, device=inputs_embeds.device + ) + return position_ids.unsqueeze(0).expand(input_shape).contiguous() + past_key_values_length + + @staticmethod + # Copied from transformers.models.roberta.modeling_roberta.RobertaEmbeddings.create_position_ids_from_input_ids + def create_position_ids_from_input_ids(input_ids, padding_idx, past_key_values_length=0): + """ + Replace non-padding symbols with their position numbers. Position numbers begin at padding_idx+1. Padding symbols + are ignored. This is modified from fairseq's `utils.make_positions`. + + Args: + x: torch.Tensor x: + + Returns: torch.Tensor + """ + # The series of casts and type-conversions here are carefully balanced to both work with ONNX export and XLA. + mask = input_ids.ne(padding_idx).int() + incremental_indices = (torch.cumsum(mask, dim=1).type_as(mask) + past_key_values_length) * mask + return incremental_indices.long() + padding_idx + + +class SeamlessM4Tv2Attention(nn.Module): + """Multi-headed attention from 'Attention Is All You Need' paper""" + + # Copied from transformers.models.bart.modeling_bart.BartAttention.__init__ with Bart->SeamlessM4Tv2 + def __init__( + self, + embed_dim: int, + num_heads: int, + dropout: float = 0.0, + is_decoder: bool = False, + bias: bool = True, + is_causal: bool = False, + config: SeamlessM4Tv2Config | None = None, + layer_idx: int | None = None, + ): + super().__init__() + self.embed_dim = embed_dim + self.num_heads = num_heads + self.dropout = dropout + self.head_dim = embed_dim // num_heads + self.config = config + + if (self.head_dim * num_heads) != self.embed_dim: + raise ValueError( + f"embed_dim must be divisible by num_heads (got `embed_dim`: {self.embed_dim}" + f" and `num_heads`: {num_heads})." + ) + self.scaling = self.head_dim**-0.5 + self.is_decoder = is_decoder + self.is_causal = is_causal + self.layer_idx = layer_idx + if layer_idx is None and self.is_decoder: + logger.warning_once( + f"Instantiating a decoder {self.__class__.__name__} without passing `layer_idx` is not recommended and " + "will lead to errors during the forward call, if caching is used. Please make sure to provide a `layer_idx` " + "when creating this class." + ) + + self.k_proj = nn.Linear(embed_dim, embed_dim, bias=bias) + self.v_proj = nn.Linear(embed_dim, embed_dim, bias=bias) + self.q_proj = nn.Linear(embed_dim, embed_dim, bias=bias) + self.out_proj = nn.Linear(embed_dim, embed_dim, bias=bias) + + def forward( + self, + hidden_states: torch.Tensor, + encoder_hidden_states: torch.Tensor | None = None, + past_key_values: Cache | None = None, + attention_mask: torch.Tensor | None = None, + output_attentions: bool = False, + cache_position: torch.Tensor | None = None, + ) -> tuple[torch.Tensor, torch.Tensor | None, tuple[torch.Tensor] | None]: + """Input shape: Batch x Time x Channel""" + + is_cross_attention = encoder_hidden_states is not None + batch_size, seq_length = hidden_states.shape[:2] + + is_updated = False + if past_key_values is not None: + if isinstance(past_key_values, EncoderDecoderCache): + is_updated = past_key_values.is_updated.get(self.layer_idx) + if is_cross_attention: + # after the first generated id, we can subsequently re-use all key/value_states from cache + curr_past_key_values = past_key_values.cross_attention_cache + else: + curr_past_key_values = past_key_values.self_attention_cache + else: + curr_past_key_values = past_key_values + + current_states = encoder_hidden_states if is_cross_attention else hidden_states + if is_cross_attention and past_key_values is not None and is_updated: + # reuse k,v, cross_attentions + key_states = curr_past_key_values.layers[self.layer_idx].keys + value_states = curr_past_key_values.layers[self.layer_idx].values + else: + key_states = self.k_proj(current_states) + value_states = self.v_proj(current_states) + key_states = key_states.view(batch_size, -1, self.num_heads, self.head_dim).transpose(1, 2) + value_states = value_states.view(batch_size, -1, self.num_heads, self.head_dim).transpose(1, 2) + + if past_key_values is not None: + # save all key/value_states to cache to be re-used for fast auto-regressive generation + cache_position = cache_position if not is_cross_attention else None + key_states, value_states = curr_past_key_values.update( + key_states, value_states, self.layer_idx, {"cache_position": cache_position} + ) + # set flag that curr layer for cross-attn is already updated so we can re-use in subsequent calls + if is_cross_attention and isinstance(past_key_values, EncoderDecoderCache): + past_key_values.is_updated[self.layer_idx] = True + + query_states = self.q_proj(hidden_states) + query_states = query_states.reshape(batch_size, seq_length, self.num_heads, self.head_dim).transpose(1, 2) + query_states = query_states * self.scaling + attention_scores = torch.matmul(query_states, key_states.transpose(-1, -2)) + + if attention_mask is not None: + attention_scores = attention_scores + attention_mask + + # (batch_size, n_heads, seq_length, key_length) + attn_weights = nn.functional.softmax(attention_scores.float(), dim=-1).type_as(attention_scores) + attn_weights = nn.functional.dropout(attn_weights, p=self.dropout, training=self.training) + + # attn_output = torch.bmm(attn_probs, value_states) ? + context_states = torch.matmul(attn_weights, value_states) + # attn_output = attn_output.view(bsz, self.num_heads, tgt_len, self.head_dim) ? + context_states = context_states.permute(0, 2, 1, 3).contiguous().view(batch_size, seq_length, -1) + attn_output = self.out_proj(context_states) + + return attn_output, attn_weights + + +# Copied from transformers.models.nllb_moe.modeling_nllb_moe.NllbMoeDenseActDense with NllbMoe->SeamlessM4Tv2,DenseActDense->FeedForwardNetwork, d_model->hidden_size +class SeamlessM4Tv2FeedForwardNetwork(nn.Module): + def __init__(self, config: SeamlessM4Tv2Config, ffn_dim: int): + super().__init__() + self.fc1 = nn.Linear(config.hidden_size, ffn_dim) + self.fc2 = nn.Linear(ffn_dim, config.hidden_size) + self.dropout = nn.Dropout(config.activation_dropout) + self.act = ACT2FN[config.activation_function] + + def forward(self, hidden_states: torch.Tensor): + hidden_states = self.fc1(hidden_states) + hidden_states = self.act(hidden_states) + hidden_states = self.dropout(hidden_states) + if ( + isinstance(self.fc2.weight, torch.Tensor) + and hidden_states.dtype != self.fc2.weight.dtype + and (self.fc2.weight.dtype != torch.int8 and self.fc2.weight.dtype != torch.uint8) + ): + hidden_states = hidden_states.to(self.fc2.weight.dtype) + hidden_states = self.fc2(hidden_states) + return hidden_states + + +# Copied from transformers.models.seamless_m4t.modeling_seamless_m4t.SeamlessM4TEncoderLayer with SeamlessM4T->SeamlessM4Tv2 +class SeamlessM4Tv2EncoderLayer(GradientCheckpointingLayer): + def __init__(self, config: SeamlessM4Tv2Config, encoder_ffn_dim=None, encoder_attention_heads=None): + super().__init__() + encoder_ffn_dim = config.encoder_ffn_dim if encoder_ffn_dim is None else encoder_ffn_dim + encoder_attention_heads = ( + config.encoder_attention_heads if encoder_attention_heads is None else encoder_attention_heads + ) + + self.embed_dim = config.hidden_size + self.self_attn = SeamlessM4Tv2Attention( + embed_dim=self.embed_dim, + num_heads=encoder_attention_heads, + dropout=config.attention_dropout, + ) + self.attn_dropout = nn.Dropout(config.dropout) + self.self_attn_layer_norm = nn.LayerNorm(self.embed_dim) + + self.ffn = SeamlessM4Tv2FeedForwardNetwork(config, ffn_dim=encoder_ffn_dim) + + self.ffn_layer_norm = nn.LayerNorm(config.hidden_size) + self.ffn_dropout = nn.Dropout(config.activation_dropout) + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.Tensor, + output_attentions: bool = False, + ) -> torch.Tensor: + """ + Args: + hidden_states (`torch.FloatTensor`): + input to the layer of shape `(batch, seq_len, embed_dim)` + attention_mask (`torch.FloatTensor`): + attention mask of size `(batch, 1, tgt_len, src_len)` where padding elements are indicated by very + large negative values. + """ + residual = hidden_states + hidden_states = self.self_attn_layer_norm(hidden_states) + hidden_states, attn_weights = self.self_attn( + hidden_states=hidden_states, + attention_mask=attention_mask, + output_attentions=output_attentions, + ) + hidden_states = self.attn_dropout(hidden_states) + hidden_states = residual + hidden_states + + residual = hidden_states + + hidden_states = self.ffn_layer_norm(hidden_states) + + hidden_states = self.ffn(hidden_states) + hidden_states = self.ffn_dropout(hidden_states) + + hidden_states = residual + hidden_states + + outputs = (hidden_states,) + + if output_attentions: + outputs += (attn_weights,) + + return outputs + + +# Copied from transformers.models.seamless_m4t.modeling_seamless_m4t.SeamlessM4TDecoderLayer with SeamlessM4T->SeamlessM4Tv2 +class SeamlessM4Tv2DecoderLayer(GradientCheckpointingLayer): + def __init__( + self, config: SeamlessM4Tv2Config, decoder_ffn_dim=None, decoder_attention_heads=None, layer_idx=None + ): + super().__init__() + decoder_ffn_dim = config.decoder_ffn_dim if decoder_ffn_dim is None else decoder_ffn_dim + decoder_attention_heads = ( + config.decoder_attention_heads if decoder_attention_heads is None else decoder_attention_heads + ) + + self.embed_dim = config.hidden_size + self.self_attn = SeamlessM4Tv2Attention( + embed_dim=self.embed_dim, + num_heads=decoder_attention_heads, + dropout=config.attention_dropout, + is_decoder=True, + layer_idx=layer_idx, + ) + self.dropout = config.dropout + self.activation_fn = ACT2FN[config.activation_function] + self.attn_dropout = nn.Dropout(config.dropout) + + self.self_attn_layer_norm = nn.LayerNorm(self.embed_dim) + self.cross_attention = SeamlessM4Tv2Attention( + self.embed_dim, + decoder_attention_heads, + config.attention_dropout, + is_decoder=True, + layer_idx=layer_idx, + ) + self.cross_attention_layer_norm = nn.LayerNorm(self.embed_dim) + + self.ffn = SeamlessM4Tv2FeedForwardNetwork(config, ffn_dim=decoder_ffn_dim) + + self.ffn_layer_norm = nn.LayerNorm(config.hidden_size) + self.ffn_dropout = nn.Dropout(config.activation_dropout) + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.Tensor | None = None, + encoder_hidden_states: torch.Tensor | None = None, + encoder_attention_mask: torch.Tensor | None = None, + past_key_values: Cache | None = None, + output_attentions: bool | None = False, + use_cache: bool | None = True, + cache_position: torch.Tensor | None = None, + ) -> torch.Tensor: + """ + Args: + hidden_states (`torch.FloatTensor`): + input to the layer of shape `(batch, seq_len, embed_dim)` + attention_mask (`torch.FloatTensor`): + attention mask of size `(batch, 1, tgt_len, src_len)` where padding elements are indicated by very + large negative values. + encoder_hidden_states (`torch.FloatTensor`): + cross attention input to the layer of shape `(batch, seq_len, embed_dim)` + encoder_attention_mask (`torch.FloatTensor`): + encoder attention mask of size `(batch, 1, tgt_len, src_len)` where padding elements are indicated by + very large negative values. + past_key_values (`Cache`): + cached past key and value projection states + output_attentions (`bool`, *optional*): + Whether or not to return the attentions tensors of all attention layers. See `attentions` under + returned tensors for more detail. + """ + residual = hidden_states + hidden_states = self.self_attn_layer_norm(hidden_states) + + # Self Attention + hidden_states, self_attn_weights = self.self_attn( + hidden_states=hidden_states, + past_key_values=past_key_values, + attention_mask=attention_mask, + output_attentions=output_attentions, + cache_position=cache_position, + ) + hidden_states = self.attn_dropout(hidden_states) + hidden_states = residual + hidden_states + + # Cross-Attention Block + cross_attn_weights = None + if encoder_hidden_states is not None: + residual = hidden_states + hidden_states = self.cross_attention_layer_norm(hidden_states) + + hidden_states, cross_attn_weights = self.cross_attention( + hidden_states=hidden_states, + encoder_hidden_states=encoder_hidden_states, + past_key_values=past_key_values, + attention_mask=encoder_attention_mask, + output_attentions=output_attentions, + cache_position=cache_position, + ) + hidden_states = self.attn_dropout(hidden_states) + hidden_states = residual + hidden_states + + # Fully Connected + residual = hidden_states + + hidden_states = self.ffn_layer_norm(hidden_states) + + hidden_states = self.ffn(hidden_states) + hidden_states = self.ffn_dropout(hidden_states) + + hidden_states = residual + hidden_states + + return hidden_states, self_attn_weights, cross_attn_weights + + +class SeamlessM4Tv2TextToUnitDecoderLayer(GradientCheckpointingLayer): + def __init__(self, config: SeamlessM4Tv2Config, decoder_ffn_dim=None, decoder_attention_heads=None): + super().__init__() + decoder_ffn_dim = config.decoder_ffn_dim if decoder_ffn_dim is None else decoder_ffn_dim + decoder_attention_heads = ( + config.decoder_attention_heads if decoder_attention_heads is None else decoder_attention_heads + ) + self.dropout = config.dropout + self.embed_dim = config.hidden_size + + self.self_attn = SeamlessM4Tv2Attention( + embed_dim=self.embed_dim, + num_heads=decoder_attention_heads, + dropout=config.attention_dropout, + is_decoder=True, + ) + self.self_attn_layer_norm = nn.LayerNorm(self.embed_dim) + + self.conv1 = nn.Conv1d(self.embed_dim, self.embed_dim, kernel_size=7, stride=1, padding="same") + self.activation_fn = ACT2FN[config.activation_function] + self.conv2 = nn.Conv1d(self.embed_dim, self.embed_dim, kernel_size=7, stride=1, padding="same") + + self.conv_layer_norm = nn.LayerNorm(config.hidden_size) + self.conv_dropout = nn.Dropout(self.dropout) + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.Tensor | None = None, + padding_mask: torch.Tensor | None = None, + output_attentions: bool | None = False, + ) -> torch.Tensor: + """ + Args: + hidden_states (`torch.FloatTensor`): + input to the layer of shape `(batch, seq_len, embed_dim)` + attention_mask (`torch.FloatTensor`): + attention mask of size `(batch, 1, tgt_len, src_len)` where padding elements are indicated by very + large negative values. + padding_mask (`torch.Tensor` of shape `(batch_size, sequence_length)`, *optional*): + Indicates which inputs are to be ignored due to padding, where elements are either 1 for *not masked* + or 0 for *masked* + output_attentions (`bool`, *optional*): + Whether or not to return the attentions tensors of all attention layers. See `attentions` under + returned tensors for more detail. + """ + residual = hidden_states + + # Self Attention + hidden_states, self_attn_weights = self.self_attn( + hidden_states=hidden_states, + attention_mask=attention_mask, + output_attentions=output_attentions, + ) + hidden_states = residual + hidden_states + hidden_states = self.self_attn_layer_norm(hidden_states) + + # Conv + residual = hidden_states + + # Apply padding mask to avoid leaking padded positions in the convolution layer + if padding_mask is not None: + hidden_states = hidden_states.masked_fill(~padding_mask.bool().unsqueeze(-1), 0.0) + hidden_states = self.conv1(hidden_states.transpose(1, 2)).transpose(1, 2) + + if padding_mask is not None: + hidden_states = hidden_states.masked_fill(~padding_mask.bool().unsqueeze(-1), 0.0) + + hidden_states = self.activation_fn(hidden_states) + hidden_states = self.conv2(hidden_states.transpose(1, 2)).transpose(1, 2) + + hidden_states = self.conv_dropout(hidden_states) + hidden_states = residual + hidden_states + hidden_states = self.conv_layer_norm(hidden_states) + + return hidden_states, self_attn_weights + + +############ SUB-MODELS related code ################ + + +@auto_docstring +class SeamlessM4Tv2PreTrainedModel(PreTrainedModel): + config: SeamlessM4Tv2Config + base_model_prefix = "seamless_m4t_v2" + supports_gradient_checkpointing = True + _no_split_modules = [ + "SeamlessM4Tv2EncoderLayer", + "SeamlessM4Tv2DecoderLayer", + "SeamlessM4Tv2ConformerEncoderLayer", + "SeamlessM4Tv2TextToUnitDecoderLayer", + ] + + @torch.no_grad() + def _init_weights(self, module: nn.Module): + """Initialize the weights""" + std = self.config.initializer_range + if isinstance(module, nn.Linear): + init.normal_(module.weight, mean=0.0, std=std) + if module.bias is not None: + init.zeros_(module.bias) + elif isinstance(module, nn.Embedding): + init.normal_(module.weight, mean=0.0, std=std) + # Here we need the check explicitly, as we slice the weight in the `zeros_` call, so it looses the flag + if module.padding_idx is not None and not getattr(module.weight, "_is_hf_initialized", False): + init.zeros_(module.weight[module.padding_idx]) + elif isinstance(module, SeamlessM4Tv2ConformerSelfAttention): + if hasattr(module, "pos_bias_u"): + init.xavier_uniform_(module.pos_bias_u) + if hasattr(module, "pos_bias_v"): + init.xavier_uniform_(module.pos_bias_v) + elif isinstance(module, SeamlessM4Tv2ConformerFeatureProjection): + k = math.sqrt(1 / module.projection.in_features) + init.uniform_(module.projection.weight, a=-k, b=k) + init.uniform_(module.projection.bias, a=-k, b=k) + elif isinstance(module, SeamlessM4Tv2TextToUnitDecoder): + init.ones_(module.pos_emb_alpha_char) + init.ones_(module.pos_emb_alpha) + elif isinstance(module, nn.LayerNorm): + init.zeros_(module.bias) + init.ones_(module.weight) + elif isinstance(module, (nn.Conv1d, nn.ConvTranspose1d)): + init.kaiming_normal_(module.weight) + if module.bias is not None: + k = math.sqrt(module.groups / (module.in_channels * module.kernel_size[0])) + init.uniform_(module.bias, a=-k, b=k) + elif isinstance(module, SeamlessM4Tv2SinusoidalPositionalEmbedding): + emb_weights = module.get_embedding( + module.num_positions + module.offset, module.embedding_dim, module.padding_idx + ) + init.copy_(module.weights, emb_weights) + + # Copied from transformers.models.seamless_m4t.modeling_seamless_m4t.SeamlessM4TPreTrainedModel._compute_sub_sample_lengths_from_attention_mask + def _compute_sub_sample_lengths_from_attention_mask(self, attention_mask): + kernel_size, stride = self.config.adaptor_kernel_size, self.config.adaptor_stride + pad = kernel_size // 2 + seq_lens = attention_mask.size(1) - (1 - attention_mask.int()).sum(1) + + seq_lens = ((seq_lens + 2 * pad - kernel_size) / stride) + 1 + + return seq_lens.floor() + + def _indices_to_subwords(self, input_ids): + """ + Returns the corresponding text string for each input id. + """ + if not hasattr(self.generation_config, "id_to_text"): + raise ValueError( + """This model generation config doesn't have a `id_to_text` key which maps + token ids to subwords. Make sure to load the right generation config.""" + ) + batch_size, sequence_len = input_ids.shape + + subwords_batch = [] + for batch_id in range(batch_size): + subwords = [] + for i in range(sequence_len): + subword = self.generation_config.id_to_text.get(str(input_ids[batch_id, i].item())) + subwords.append(str(subword)) + subwords_batch.append(subwords) + return subwords_batch + + def _count_character_length_in_subword( + self, + input_ids, + subwords_batch, + merge_space_with_prev_subword=False, + pad_token_id=0, + unk_token_id=1, + space="▁", + ): + """ + Counts the number of characters per text string associated with the input token id. + + Args: + input_ids (`torch.Tensor` of shape `(batch_size, sequence_length)`): + Indices of input sequence tokens in the vocabulary. + subwords_batch (`list[list[str]]` of shape `(batch_size, sequence_length)`): + Corresponding text string for each input id. + merge_space_with_prev_subword (`bool`, *optional*, defaults to `False`): + Indicates if the space character is merged with the previous subword. If `False`, it will be merged + with the next subword. + pad_token_id (`int`, *optional*, defaults to 0): + The id of the _padding_ text token. If it is encountered when calculating the length of a subword + sample, the lengths of subsequent subwords will be set to 0. + unk_token_id (`int`, *optional*, defaults to 1): + The id of the _unknown_ text token. Associated to a subword of length 1. + space (`str`, *optional*, defaults to `"▁"`): + The space character. + """ + batch_size, _ = input_ids.shape + + char_count_per_id = input_ids.new_zeros(input_ids.size()) + + subword_lens = input_ids.ne(pad_token_id).sum(1) + + for batch_id in range(batch_size): + # We slice out the tensor till the padding index. + subword_indices = input_ids[batch_id, : subword_lens[batch_id]] + subwords = subwords_batch[batch_id][: subword_lens[batch_id]] + + is_next_start_with_space = [ + len(subwords[i + 1]) > 1 and subwords[i + 1][0] == space if i < len(subwords) - 1 else False + for i in range(len(subwords)) + ] + is_punc = [ + len(subwords[i]) == 1 + and not subwords[i].isalpha() + and not subwords[i].isnumeric() + and subwords[i] != space + for i in range(len(subwords)) + ] + for i, (subword_idx, subword) in enumerate(zip(subword_indices, subwords)): + if subword_idx == pad_token_id: + break + + if subword_idx == unk_token_id: + # We set char_len to 1 for an unk token. + char_len = 1 + + if merge_space_with_prev_subword and is_next_start_with_space[i]: + char_len += 1 + else: + # By default, spaces are merged with the next subword. + # char_len includes the space. + char_len = len(subword) + + if merge_space_with_prev_subword: + # Add the space for the next subword. + if is_next_start_with_space[i]: + char_len += 1 + # Subtract the space for the current subword. + if i > 0 and is_next_start_with_space[i - 1]: + char_len -= 1 + else: + # Merge space with punctuation mark by default. + if is_punc[i] and is_next_start_with_space[i]: + char_len += 1 + # Subtract the space for the subword succeeding the punctuation mark. + elif i > 0 and is_punc[i - 1] and is_next_start_with_space[i - 1]: + char_len -= 1 + + char_count_per_id[batch_id, i] = char_len + + return char_count_per_id + + def _get_char_input_ids(self, input_ids, subwords_batch, char_count_per_id, pad_token_id=0, unk_token_id=1): + """ + Returns the corresponding character input id for each character of `subwords_batch`. + + Args: + input_ids (`torch.Tensor` of shape `(batch_size, sequence_length)`): + Indices of input sequence tokens in the vocabulary. + subwords_batch (`list[list[str]]` of shape `(batch_size, sequence_length)`): + Corresponding text string for each input id. + char_count_per_id (`torch.Tensor` of shape `(batch_size, sequence_length)`): + Number of characters per input id. + pad_token_id (`int`, *optional*, defaults to 0): + The id of the _padding_ text token. If it is encountered when calculating the length of a subword + sample, the lengths of subsequent subwords will be set to 0. + unk_token_id (`int`, *optional*, defaults to 1): + The id of the _unknown_ text token. Associated to a subword of length 1. + Returns: + `torch.Tensor`: Tensor of shape `(batch_size, char_sequence_length)` containing the id of each character. + """ + if not hasattr(self.generation_config, "char_to_id"): + raise ValueError( + """This model generation config doesn't have a `char_to_id` key which maps + characters to character ids. Make sure to load the right generation config.""" + ) + + batch_size = input_ids.shape[0] + max_len = int(char_count_per_id.sum(1).max().item()) + + char_seqs = input_ids.new_zeros((batch_size, max_len)).fill_(pad_token_id) + + subword_lens = input_ids.ne(pad_token_id).sum(1) + + for batch_id in range(batch_size): + total = 0 + subword_indices = input_ids[batch_id, : subword_lens[batch_id]] + subwords = subwords_batch[batch_id][: subword_lens[batch_id]] + for subword_idx, subword in zip(subword_indices, subwords): + if subword_idx == unk_token_id: + char_ids = [unk_token_id] + else: + # Get char token indices corresponding to the subwords. + char_ids = [self.generation_config.char_to_id.get(ch, unk_token_id) for ch in list(subword)] + char_seq_len = len(char_ids) + char_seqs[batch_id, total : total + char_seq_len] = torch.tensor(char_ids).to(char_seqs) + total += char_seq_len + return char_seqs + + def _hard_upsample(self, hidden_states, durations): + """ + Repeats the time dimension of each sample in the batch based on the corresponding duration. + + Args: + hidden_states (`torch.Tensor` of shape `(batch_size, sequence_length, *)`, *optional*): + The sequence to repeat, where `*` is any number of sequence-specific dimensions including none. + durations (`torch.Tensor` of shape `(batch_size, sequence_length)`, *optional*): + Indicates how many times to repeat time segments. + """ + if hidden_states.size(0) == 1: + hidden_states = torch.repeat_interleave(hidden_states, durations.view(-1), dim=1) + else: + # if batched sample, need to interleave per sample, and pad -> loss of parallelism + if hidden_states.shape[0] > 1 and self.training: + logger.warning_once( + """`self.training=True` and you use batching. You lose parallelism during the hifigan + forward pass because the samples are interleaved.""" + ) + hidden_states = [ + torch.repeat_interleave(hidden_state, duration, dim=0) + for (hidden_state, duration) in zip(hidden_states, durations) + ] + + hidden_states = nn.utils.rnn.pad_sequence(hidden_states, batch_first=True) + + return hidden_states + + +@auto_docstring( + custom_intro=""" + Transformer speech encoder consisting of *config.speech_encoder_layers* conformer self attention layers. + Each layer is a [`SeamlessM4Tv2ConformerEncoderLayer`]. + """ +) +# Copied from transformers.models.seamless_m4t.modeling_seamless_m4t.SeamlessM4TSpeechEncoder with SeamlessM4T->SeamlessM4Tv2 +class SeamlessM4Tv2SpeechEncoder(SeamlessM4Tv2PreTrainedModel): + main_input_name = "input_features" + input_modalities = "audio" + + def __init__(self, config: SeamlessM4Tv2Config): + super().__init__(config) + + self.feature_projection = SeamlessM4Tv2ConformerFeatureProjection(config) + self.encoder = SeamlessM4Tv2ConformerEncoder(config) + self.intermediate_ffn = SeamlessM4Tv2ConformerFeedForward(config, act_fn="relu", dropout=0.0) + self.adapter = SeamlessM4Tv2ConformerAdapter(config) if config.add_adapter else None + self.inner_layer_norm = nn.LayerNorm(config.hidden_size) + + # Initialize weights and apply final processing + self.post_init() + + def forward( + self, + input_features: torch.Tensor | None, + attention_mask: torch.Tensor | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + **kwargs, + ) -> tuple | Wav2Vec2BaseModelOutput: + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + if input_features is None: + raise ValueError( + """Both `input_features` and `inputs_embeds` are `None` in `SeamlessM4Tv2SpeechEncoder.forward`. + Make sure one of them is not `None`.""" + ) + + hidden_states = self.feature_projection(input_features) + + encoder_outputs = self.encoder( + hidden_states, + attention_mask=attention_mask, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + + hidden_states = encoder_outputs[0] + + expanded_hidden_states = self.intermediate_ffn(hidden_states) + hidden_states = hidden_states + 0.5 * expanded_hidden_states + + if self.adapter is not None: + hidden_states = self.adapter(hidden_states, attention_mask=attention_mask) + + hidden_states = self.inner_layer_norm(hidden_states) + + if not return_dict: + return (hidden_states,) + encoder_outputs[1:] + + return Wav2Vec2BaseModelOutput( + last_hidden_state=hidden_states, + hidden_states=encoder_outputs.hidden_states, + attentions=encoder_outputs.attentions, + ) + + +# inspired from MBart and NllbMoe +@auto_docstring( + custom_intro=""" + Transformer encoder consisting of *config.encoder_layers* self attention layers. Each layer is a [`SeamlessM4Tv2EncoderLayer`]. + """ +) +# Copied from transformers.models.seamless_m4t.modeling_seamless_m4t.SeamlessM4TEncoder with SeamlessM4T->SeamlessM4Tv2 +class SeamlessM4Tv2Encoder(SeamlessM4Tv2PreTrainedModel): + def __init__( + self, + config: SeamlessM4Tv2Config, + embed_tokens: nn.Embedding | None = None, + is_t2u_encoder: bool = False, + ): + r""" + embed_tokens (`nn.Embedding`, *optional*): + Input embedding + is_t2u_encoder (`bool`, *optional*, defaults to `False`): + indicates if it belongs to the text-to-units model, in which case it won't have input embeddings + """ + super().__init__(config) + + self.dropout = config.dropout + self.layerdrop = config.encoder_layerdrop + self.padding_idx = config.pad_token_id + embed_dim = config.hidden_size + + self.is_t2u_encoder = is_t2u_encoder + self.max_source_positions = config.max_position_embeddings + + if not self.is_t2u_encoder: + embed_scale = math.sqrt(embed_dim) if config.scale_embedding else 1.0 + + self.embed_tokens = SeamlessM4Tv2ScaledWordEmbedding( + config.vocab_size, embed_dim, self.padding_idx, embed_scale=embed_scale + ) + + if embed_tokens is not None: + self.embed_tokens.weight = embed_tokens.weight + + self.embed_positions = SeamlessM4Tv2SinusoidalPositionalEmbedding( + self.max_source_positions, + embed_dim, + self.padding_idx, + ) + + layers = [] + for _ in range(config.encoder_layers): + layers.append( + SeamlessM4Tv2EncoderLayer( + config, + encoder_attention_heads=config.encoder_attention_heads, + encoder_ffn_dim=config.encoder_ffn_dim, + ) + ) + + self.layers = nn.ModuleList(layers) + + self.layer_norm = nn.LayerNorm(config.hidden_size) + + self.gradient_checkpointing = False + # Initialize weights and apply final processing + self.post_init() + + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.Tensor | None = None, + inputs_embeds: torch.FloatTensor | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + **kwargs, + ) -> tuple | BaseModelOutput: + r""" + Args: + input_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`): + Indices of input sequence tokens in the vocabulary. Padding will be ignored by default should you + provide it. + + Indices can be obtained using [`AutoTokenizer`]. See [`PreTrainedTokenizer.encode`] and + [`PreTrainedTokenizer.__call__`] for details. + + [What are input IDs?](../glossary#input-ids) + attention_mask (`torch.Tensor` of shape `(batch_size, sequence_length)`, *optional*): + Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`: + + - 1 for tokens that are **not masked**, + - 0 for tokens that are **masked**. + + [What are attention masks?](../glossary#attention-mask) + inputs_embeds (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*): + Optionally, instead of passing `input_ids` you can choose to directly pass an embedded representation. + This is useful if you want more control over how to convert `input_ids` indices into associated vectors + than the model's internal embedding lookup matrix. + output_attentions (`bool`, *optional*): + Whether or not to return the attentions tensors of all attention layers. See `attentions` under + returned tensors for more detail. + output_hidden_states (`bool`, *optional*): + Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors + for more detail. + return_dict (`bool`, *optional*): + Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple. + """ + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + if input_ids is not None and self.is_t2u_encoder: + raise ValueError( + "You cannot pass input_ids to the encoder of the text_to_units model. Pass inputs_embeds instead." + ) + + # retrieve input_ids and inputs_embeds + if input_ids is not None and inputs_embeds is not None: + raise ValueError("You cannot specify both input_ids and inputs_embeds at the same time") + elif input_ids is not None: + input = input_ids + input_shape = input.shape + input_ids = input_ids.view(-1, input_shape[-1]) + elif inputs_embeds is not None: + input = inputs_embeds[:, :, -1] + else: + raise ValueError("You have to specify either input_ids or inputs_embeds") + + if inputs_embeds is None: + inputs_embeds = self.embed_tokens(input_ids) + + if not self.is_t2u_encoder: + embed_pos = self.embed_positions(input) + + hidden_states = inputs_embeds + embed_pos.to(inputs_embeds.device) + else: + hidden_states = inputs_embeds + + hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training) + + # expand attention_mask + if attention_mask is not None: + attention_mask = create_bidirectional_mask( + config=self.config, + inputs_embeds=inputs_embeds, + attention_mask=attention_mask, + ) + + encoder_states = () if output_hidden_states else None + all_attentions = () if output_attentions else None + + for idx, encoder_layer in enumerate(self.layers): + if output_hidden_states: + encoder_states = encoder_states + (hidden_states,) + # add LayerDrop (see https://huggingface.co/papers/1909.11556 for description) + to_drop = False + if self.training: + dropout_probability = torch.rand([]) + if dropout_probability < self.layerdrop: # skip the layer + to_drop = True + + if to_drop: + layer_outputs = (None, None) + else: + layer_outputs = encoder_layer( + hidden_states, + attention_mask, + output_attentions=output_attentions, + ) + + hidden_states = layer_outputs[0] + + if output_attentions: + all_attentions = all_attentions + (layer_outputs[1],) + + hidden_states = self.layer_norm(hidden_states) + + if output_hidden_states: + encoder_states = encoder_states + (hidden_states,) + + if not return_dict: + return tuple(v for v in [hidden_states, encoder_states, all_attentions] if v is not None) + return BaseModelOutput( + last_hidden_state=hidden_states, hidden_states=encoder_states, attentions=all_attentions + ) + + +@auto_docstring( + custom_intro=""" + Transformer decoder consisting of *config.decoder_layers* layers. Each layer is a [`SeamlessM4Tv2DecoderLayer`]. + """ +) +# Copied from transformers.models.seamless_m4t.modeling_seamless_m4t.SeamlessM4TDecoder with SeamlessM4T->SeamlessM4Tv2 +class SeamlessM4Tv2Decoder(SeamlessM4Tv2PreTrainedModel): + def __init__( + self, + config: SeamlessM4Tv2Config, + embed_tokens: nn.Embedding | None = None, + ): + r""" + embed_tokens (`nn.Embedding`, *optional*): + Input embedding + """ + super().__init__(config) + self.dropout = config.dropout + self.layerdrop = config.decoder_layerdrop + self.padding_idx = config.pad_token_id + self.vocab_size = config.vocab_size + self.max_target_positions = config.max_position_embeddings + embed_scale = math.sqrt(config.hidden_size) if config.scale_embedding else 1.0 + + if embed_tokens is not None: + # if embed_tokens defined, use its shape instead + self.embed_tokens = SeamlessM4Tv2ScaledWordEmbedding( + embed_tokens.num_embeddings, embed_tokens.embedding_dim, self.padding_idx, embed_scale=embed_scale + ) + self.embed_tokens.weight = embed_tokens.weight + else: + self.embed_tokens = SeamlessM4Tv2ScaledWordEmbedding( + self.vocab_size, config.hidden_size, self.padding_idx, embed_scale=embed_scale + ) + + self.embed_positions = SeamlessM4Tv2SinusoidalPositionalEmbedding( + self.max_target_positions, + config.hidden_size, + padding_idx=self.padding_idx, + ) + + layers = [] + for i in range(config.decoder_layers): + layers.append( + SeamlessM4Tv2DecoderLayer( + config, + decoder_attention_heads=config.decoder_attention_heads, + decoder_ffn_dim=config.decoder_ffn_dim, + layer_idx=i, + ) + ) + self.layers = nn.ModuleList(layers) + self.layer_norm = nn.LayerNorm(config.hidden_size) + + self.gradient_checkpointing = False + # Initialize weights and apply final processing + self.post_init() + + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.Tensor | None = None, + encoder_hidden_states: torch.FloatTensor | None = None, + encoder_attention_mask: torch.LongTensor | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.FloatTensor | None = None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + cache_position: torch.Tensor | None = None, + **kwargs, + ) -> tuple | BaseModelOutputWithPastAndCrossAttentions: + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + use_cache = use_cache if use_cache is not None else self.config.use_cache + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + # retrieve input_ids and inputs_embeds + if input_ids is not None and inputs_embeds is not None: + raise ValueError("You cannot specify both decoder_input_ids and decoder_inputs_embeds at the same time") + elif input_ids is not None: + input = input_ids + input_shape = input.size() + input_ids = input_ids.view(-1, input_shape[-1]) + elif inputs_embeds is not None: + input_shape = inputs_embeds.size()[:-1] + input = inputs_embeds[:, :, -1] + else: + raise ValueError("You have to specify either decoder_input_ids or decoder_inputs_embeds") + + if inputs_embeds is None: + inputs_embeds = self.embed_tokens(input_ids) + + if self.gradient_checkpointing and self.training: + if use_cache: + logger.warning_once( + "`use_cache=True` is incompatible with gradient checkpointing`. Setting `use_cache=False`..." + ) + use_cache = False + + # initialize `past_key_values` + if use_cache and past_key_values is None: + past_key_values = EncoderDecoderCache(DynamicCache(config=self.config), DynamicCache(config=self.config)) + + past_key_values_length = past_key_values.get_seq_length() if past_key_values is not None else 0 + if cache_position is None: + cache_position = torch.arange( + past_key_values_length, past_key_values_length + inputs_embeds.shape[1], device=inputs_embeds.device + ) + + attention_mask = create_causal_mask( + config=self.config, + inputs_embeds=inputs_embeds, + attention_mask=attention_mask, + cache_position=cache_position, + past_key_values=past_key_values, + ) + + # expand encoder attention mask + if encoder_hidden_states is not None and encoder_attention_mask is not None: + encoder_attention_mask = create_bidirectional_mask( + config=self.config, + inputs_embeds=inputs_embeds, + attention_mask=encoder_attention_mask, + encoder_hidden_states=encoder_hidden_states, + ) + + # embed positions + positions = self.embed_positions(input, past_key_values_length=past_key_values_length) + + hidden_states = inputs_embeds + positions.to(inputs_embeds.device) + + hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training) + + # decoder layers + all_hidden_states = () if output_hidden_states else None + all_self_attns = () if output_attentions else None + all_cross_attentions = () if (output_attentions and encoder_hidden_states is not None) else None + + for idx, decoder_layer in enumerate(self.layers): + # add LayerDrop (see https://huggingface.co/papers/1909.11556 for description) + if output_hidden_states: + all_hidden_states += (hidden_states,) + if self.training: + dropout_probability = torch.rand([]) + if dropout_probability < self.layerdrop: + continue + + layer_outputs = decoder_layer( + hidden_states, + attention_mask, + encoder_hidden_states, # as a positional argument for gradient checkpointing + encoder_attention_mask=encoder_attention_mask, + past_key_values=past_key_values, + output_attentions=output_attentions, + use_cache=use_cache, + cache_position=cache_position, + ) + hidden_states = layer_outputs[0] + if output_attentions: + all_self_attns += (layer_outputs[1],) + + if encoder_hidden_states is not None: + all_cross_attentions += (layer_outputs[2],) + + hidden_states = self.layer_norm(hidden_states) + + # add hidden states from the last decoder layer + if output_hidden_states: + all_hidden_states += (hidden_states,) + + if not return_dict: + return tuple( + v + for v in [hidden_states, past_key_values, all_hidden_states, all_self_attns, all_cross_attentions] + if v is not None + ) + return BaseModelOutputWithPastAndCrossAttentions( + last_hidden_state=hidden_states, + past_key_values=past_key_values, + hidden_states=all_hidden_states, + attentions=all_self_attns, + cross_attentions=all_cross_attentions, + ) + + +@auto_docstring( + custom_intro=""" + Transformer decoder consisting of *config.decoder_layers* layers. Each layer is a [`SeamlessM4Tv2DecoderLayer`]. + """ +) +class SeamlessM4Tv2TextToUnitDecoder(SeamlessM4Tv2PreTrainedModel): + def __init__( + self, + config: SeamlessM4Tv2Config, + embed_tokens: nn.Embedding | None = None, + ): + r""" + embed_tokens (`nn.Embedding`, *optional*): + Input embedding + """ + super().__init__(config) + self.dropout = config.dropout + self.layerdrop = config.decoder_layerdrop + self.padding_idx = config.pad_token_id + self.vocab_size = config.vocab_size + self.max_target_positions = config.max_position_embeddings + self.embed_scale = math.sqrt(config.hidden_size) if config.scale_embedding else 1.0 + + if embed_tokens is not None: + # if embed_tokens defined, use its shape instead + self.embed_tokens = nn.Embedding(embed_tokens.num_embeddings, embed_tokens.embedding_dim, self.padding_idx) + self.embed_tokens.weight = embed_tokens.weight + else: + self.embed_tokens = nn.Embedding(self.vocab_size, config.hidden_size, self.padding_idx) + + self.embed_char = nn.Embedding(config.char_vocab_size, config.hidden_size) + self.embed_char_positions = SeamlessM4Tv2SinusoidalPositionalEmbedding( + self.max_target_positions, + config.hidden_size, + padding_idx=self.padding_idx, + ) + + self.pos_emb_alpha_char = nn.Parameter(torch.ones(1)) + self.pos_emb_alpha = nn.Parameter(torch.ones(1)) + self.duration_predictor = SeamlessM4Tv2VariancePredictor( + config.variance_predictor_embed_dim, + config.variance_predictor_hidden_dim, + config.variance_predictor_kernel_size, + config.variance_pred_dropout, + ) + + self.embed_positions = SeamlessM4Tv2SinusoidalPositionalEmbedding( + self.max_target_positions, + config.hidden_size, + padding_idx=self.padding_idx, + ) + + layers = [] + for _ in range(config.decoder_layers): + layers.append( + SeamlessM4Tv2TextToUnitDecoderLayer( + config, + decoder_attention_heads=config.decoder_attention_heads, + decoder_ffn_dim=config.decoder_ffn_dim, + ) + ) + self.layers = nn.ModuleList(layers) + self.layer_norm = nn.LayerNorm(config.hidden_size) + + self.gradient_checkpointing = False + # Initialize weights and apply final processing + self.post_init() + + def forward( + self, + char_input_ids: torch.LongTensor | None = None, + char_count_per_id: torch.LongTensor | None = None, + encoder_hidden_states: torch.FloatTensor | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + **kwargs, + ) -> tuple | SeamlessM4Tv2TextToUnitDecoderOutput: + r""" + Args: + char_input_ids (`torch.LongTensor` of shape `(batch_size, char_sequence_length)`): + Character indices. The correspondence between characters and indices can be found in `char_to_id`, a + dictionary in the generation configuration. + char_count_per_id (`torch.Tensor` of shape `(batch_size, encoder_sequence_length)`): + Number of characters per text input id. + encoder_hidden_states (`torch.FloatTensor` of shape `(batch_size, encoder_sequence_length, hidden_size)`): + Sequence of hidden-states at the output of the last layer of the encoder. Used in the cross-attention + of the decoder. + output_attentions (`bool`, *optional*): + Whether or not to return the attentions tensors of all attention layers. See `attentions` under + returned tensors for more detail. + output_hidden_states (`bool`, *optional*): + Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors + for more detail. + return_dict (`bool`, *optional*): + Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple. + """ + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + # create padding mask for character lengths + char_padding_mask = _compute_new_attention_mask(char_input_ids, char_count_per_id.sum(1)) + + # upsample hidden states according to characters sequence lengths + char_hidden_states = self._hard_upsample(encoder_hidden_states, char_count_per_id) + # embed char positions + char_positions = self.pos_emb_alpha_char * self.embed_char_positions(inputs_embeds=char_hidden_states) + # update char hidden states with positions and char embeddings + char_hidden_states = self.embed_char(char_input_ids) * self.embed_scale + char_positions + char_hidden_states + + # predict duration + log_dur_pred = self.duration_predictor(char_hidden_states, padding_mask=char_padding_mask) + dur_out = torch.clamp(torch.round(torch.expm1(log_dur_pred)).long(), min=1) + dur_out = dur_out.masked_fill(~char_padding_mask.bool(), 0.0) + + # upsample char hidden states according to predicted duration + char_hidden_states = self._hard_upsample(char_hidden_states, dur_out) + + positions = self.pos_emb_alpha * self.embed_positions(inputs_embeds=char_hidden_states) + hidden_states = char_hidden_states + positions + + padding_mask = _compute_new_attention_mask(hidden_states, dur_out.sum(1)) + attention_mask = create_bidirectional_mask( + config=self.config, + inputs_embeds=hidden_states, + attention_mask=padding_mask, + ) + + hidden_states = nn.functional.dropout(hidden_states, p=self.dropout, training=self.training) + + # decoder layers + all_hidden_states = () if output_hidden_states else None + all_self_attns = () if output_attentions else None + + for idx, decoder_layer in enumerate(self.layers): + # add LayerDrop (see https://huggingface.co/papers/1909.11556 for description) + if output_hidden_states: + all_hidden_states += (hidden_states,) + if self.training: + dropout_probability = torch.rand([]) + if dropout_probability < self.layerdrop: + continue + + layer_outputs = decoder_layer( + hidden_states, + attention_mask=attention_mask, + padding_mask=padding_mask, + output_attentions=output_attentions, + ) + hidden_states = layer_outputs[0] + + if output_attentions: + all_self_attns += (layer_outputs[2],) + + hidden_states = self.layer_norm(hidden_states) + + # add hidden states from the last decoder layer + if output_hidden_states: + all_hidden_states += (hidden_states,) + + if not return_dict: + return tuple(v for v in [hidden_states, all_hidden_states, all_self_attns, padding_mask] if v is not None) + return SeamlessM4Tv2TextToUnitDecoderOutput( + last_hidden_state=hidden_states, + hidden_states=all_hidden_states, + attentions=all_self_attns, + padding_mask=padding_mask, + ) + + +@auto_docstring( + custom_intro=""" + Transformer bare text-to-unit encoder-decoder. The encoder is a [`SeamlessM4Tv2Encoder`] without embeddings and the decoder is a [`SeamlessM4Tv2TextToUnitDecoder`]. + """ +) +class SeamlessM4Tv2TextToUnitModel(SeamlessM4Tv2PreTrainedModel): + # Copied from transformers.models.seamless_m4t.modeling_seamless_m4t.SeamlessM4TTextToUnitModel.__init__ with SeamlessM4T->SeamlessM4Tv2, Decoder->TextToUnitDecoder + def __init__( + self, + config: SeamlessM4Tv2Config, + embed_tokens_decoder: nn.Embedding | None = None, + ): + r""" + embed_tokens_decoder (`nn.Embedding`, *optional*): + input embedding of the decoder. + """ + super().__init__(config) + + self.encoder = SeamlessM4Tv2Encoder(config, is_t2u_encoder=True) + self.decoder = SeamlessM4Tv2TextToUnitDecoder(config, embed_tokens_decoder) + + # Initialize weights and apply final processing + self.post_init() + + def forward( + self, + input_ids: torch.LongTensor | None = None, + char_input_ids: torch.LongTensor | None = None, + char_count_per_id: torch.LongTensor | None = None, + attention_mask: torch.Tensor | None = None, + encoder_outputs: tuple[tuple[torch.FloatTensor]] | None = None, + inputs_embeds: torch.FloatTensor | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + **kwargs, + ) -> tuple[torch.Tensor] | Seq2SeqModelOutput: + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + if encoder_outputs is None: + encoder_outputs = self.encoder( + input_ids=input_ids, + attention_mask=attention_mask, + inputs_embeds=inputs_embeds, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + # If the user passed a tuple for encoder_outputs, we wrap it in a BaseModelOutput when return_dict=True + elif return_dict and not isinstance(encoder_outputs, BaseModelOutput): + encoder_outputs = BaseModelOutput( + last_hidden_state=encoder_outputs[0], + hidden_states=encoder_outputs[1] if len(encoder_outputs) > 1 else None, + attentions=encoder_outputs[2] if len(encoder_outputs) > 2 else None, + ) + + # decoder outputs consists of (dec_features, dec_hidden, dec_attn, padding_mask) + decoder_outputs = self.decoder( + char_input_ids=char_input_ids, + char_count_per_id=char_count_per_id, + encoder_hidden_states=encoder_outputs[0], + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + + if not return_dict: + return decoder_outputs + encoder_outputs + + return SeamlessM4Tv2TextToUnitOutput( + last_hidden_state=decoder_outputs.last_hidden_state, + padding_mask=decoder_outputs.padding_mask, + decoder_hidden_states=decoder_outputs.hidden_states, + decoder_attentions=decoder_outputs.attentions, + encoder_last_hidden_state=encoder_outputs.last_hidden_state, + encoder_hidden_states=encoder_outputs.hidden_states, + encoder_attentions=encoder_outputs.attentions, + ) + + +@auto_docstring( + custom_intro=""" + Transformer text-to-unit encoder-decoder with a language model head. The base encoder-decoder model is a [`SeamlessM4Tv2TextToUnitModel`]. + """ +) +class SeamlessM4Tv2TextToUnitForConditionalGeneration(SeamlessM4Tv2PreTrainedModel, GenerationMixin): + _keys_to_ignore_on_load_missing = [ + "vocoder", + "speech_encoder", + "text_encoder", + "text_decoder", + ] + _tied_weights_keys = {"lm_head.weight": "model.decoder.embed_tokens.weight"} + + # Copied from transformers.models.seamless_m4t.modeling_seamless_m4t.SeamlessM4TTextToUnitForConditionalGeneration.__init__ with SeamlessM4T->SeamlessM4Tv2 + def __init__( + self, + config: SeamlessM4Tv2Config, + embed_tokens_decoder: nn.Embedding | None = None, + ): + r""" + embed_tokens_decoder (`nn.Embedding`, *optional*): + input embedding of the decoder. + """ + # update config - used principality for bos_token_id etc. + config = copy.deepcopy(config) + for param, val in config.to_dict().items(): + if param.startswith("t2u_"): + config.__setattr__(param[4:], val) + super().__init__(config) + + self.model = SeamlessM4Tv2TextToUnitModel(config, embed_tokens_decoder) + + self.lm_head = nn.Linear(config.hidden_size, config.t2u_vocab_size, bias=False) + + # Initialize weights and apply final processing + self.post_init() + + # Copied from transformers.models.seamless_m4t.modeling_seamless_m4t.SeamlessM4TTextToUnitForConditionalGeneration.get_encoder + def get_encoder(self): + return self.model.encoder + + # Copied from transformers.models.seamless_m4t.modeling_seamless_m4t.SeamlessM4TTextToUnitForConditionalGeneration.get_decoder + def get_decoder(self): + return self.model.decoder + + # Copied from transformers.models.seamless_m4t.modeling_seamless_m4t.SeamlessM4TTextToUnitForConditionalGeneration.get_input_embeddings + def get_input_embeddings(self): + return self.model.decoder.embed_tokens + + # Copied from transformers.models.seamless_m4t.modeling_seamless_m4t.SeamlessM4TTextToUnitForConditionalGeneration.set_input_embeddings + def set_input_embeddings(self, value): + self.model.decoder.embed_tokens = value + + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + char_input_ids: torch.LongTensor | None = None, + char_count_per_id: torch.LongTensor | None = None, + attention_mask: torch.Tensor | None = None, + encoder_outputs: tuple[tuple[torch.FloatTensor]] | None = None, + inputs_embeds: torch.FloatTensor | None = None, + labels: torch.LongTensor | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + **kwargs, + ) -> Seq2SeqLMOutput | tuple[torch.FloatTensor]: + r""" + char_input_ids (`torch.LongTensor` of shape `(batch_size, char_sequence_length)`): + Character indices. The correspondence between characters and indices can be found in `char_to_id`, a + dictionary in the generation configuration. + char_count_per_id (`torch.LongTensor` of shape `(batch_size, sequence_length)`): + Number of characters per input id. + inputs_embeds (`torch.FloatTensor` of shape`(batch_size, sequence_length, hidden_size)`, *optional*): + Optionally, instead of passing `input_ids` you can choose to directly pass an embedded representation. This + is useful if you want more control over how to convert `input_ids` indices into associated vectors than the + model's internal embedding lookup matrix. + labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Labels for computing the masked language modeling loss. Indices should be in `[-100, 0, ..., + config.vocab_size]` (see `input_ids` docstring) Tokens with indices set to `-100` are ignored (masked), the + loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]` + """ + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + outputs = self.model( + input_ids, + char_input_ids=char_input_ids, + char_count_per_id=char_count_per_id, + attention_mask=attention_mask, + encoder_outputs=encoder_outputs, + inputs_embeds=inputs_embeds, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + lm_logits = self.lm_head(outputs[0]) + + masked_lm_loss = None + if labels is not None: + loss_fct = CrossEntropyLoss() + labels = labels.to(lm_logits.device) + masked_lm_loss = loss_fct(lm_logits.view(-1, self.config.vocab_size), labels.view(-1)) + + if not return_dict: + output = (lm_logits,) + outputs[1:] + return ((masked_lm_loss,) + output) if masked_lm_loss is not None else output + + return SeamlessM4Tv2TextToUnitOutput( + last_hidden_state=lm_logits, + padding_mask=outputs.padding_mask, + decoder_hidden_states=outputs.decoder_hidden_states, + decoder_attentions=outputs.decoder_attentions, + encoder_last_hidden_state=outputs.encoder_last_hidden_state, + encoder_hidden_states=outputs.encoder_hidden_states, + encoder_attentions=outputs.encoder_attentions, + loss=masked_lm_loss, + ) + + +############ VOCODER related code ################ + + +# Copied from transformers.models.speecht5.modeling_speecht5.HifiGanResidualBlock +class HifiGanResidualBlock(nn.Module): + def __init__(self, channels, kernel_size=3, dilation=(1, 3, 5), leaky_relu_slope=0.1): + super().__init__() + self.leaky_relu_slope = leaky_relu_slope + + self.convs1 = nn.ModuleList( + [ + nn.Conv1d( + channels, + channels, + kernel_size, + stride=1, + dilation=dilation[i], + padding=self.get_padding(kernel_size, dilation[i]), + ) + for i in range(len(dilation)) + ] + ) + self.convs2 = nn.ModuleList( + [ + nn.Conv1d( + channels, + channels, + kernel_size, + stride=1, + dilation=1, + padding=self.get_padding(kernel_size, 1), + ) + for _ in range(len(dilation)) + ] + ) + + def get_padding(self, kernel_size, dilation=1): + return (kernel_size * dilation - dilation) // 2 + + def apply_weight_norm(self): + weight_norm = nn.utils.weight_norm + if hasattr(nn.utils.parametrizations, "weight_norm"): + weight_norm = nn.utils.parametrizations.weight_norm + + for layer in self.convs1: + weight_norm(layer) + for layer in self.convs2: + weight_norm(layer) + + def remove_weight_norm(self): + for layer in self.convs1: + nn.utils.remove_weight_norm(layer) + for layer in self.convs2: + nn.utils.remove_weight_norm(layer) + + def forward(self, hidden_states): + for conv1, conv2 in zip(self.convs1, self.convs2): + residual = hidden_states + hidden_states = nn.functional.leaky_relu(hidden_states, self.leaky_relu_slope) + hidden_states = conv1(hidden_states) + hidden_states = nn.functional.leaky_relu(hidden_states, self.leaky_relu_slope) + hidden_states = conv2(hidden_states) + hidden_states = hidden_states + residual + return hidden_states + + +class SeamlessM4Tv2VariancePredictor(nn.Module): + def __init__(self, embed_dim, hidden_dim, kernel_size, var_pred_dropout): + super().__init__() + + self.conv1 = nn.Conv1d( + embed_dim, + hidden_dim, + kernel_size=kernel_size, + padding="same", + ) + self.activation_function = nn.ReLU() + self.ln1 = nn.LayerNorm(hidden_dim) + self.dropout_module = nn.Dropout(p=var_pred_dropout) + self.conv2 = nn.Conv1d( + hidden_dim, + hidden_dim, + kernel_size=kernel_size, + padding="same", + ) + self.ln2 = nn.LayerNorm(hidden_dim) + self.proj = nn.Linear(hidden_dim, 1) + + def forward(self, hidden_states: Tensor, padding_mask: Tensor | None = None) -> Tensor: + # Input: B x T x C; Output: B x T + if padding_mask is not None: + hidden_states = hidden_states.masked_fill(~padding_mask.bool().unsqueeze(-1), 0.0) + hidden_states = self.conv1(hidden_states.transpose(1, 2)) + hidden_states = self.activation_function(hidden_states).transpose(1, 2) + hidden_states = self.dropout_module(self.ln1(hidden_states)) + if padding_mask is not None: + hidden_states = hidden_states.masked_fill(~padding_mask.bool().unsqueeze(-1), 0.0) + hidden_states = self.conv2(hidden_states.transpose(1, 2)) + hidden_states = self.activation_function(hidden_states).transpose(1, 2) + hidden_states = self.dropout_module(self.ln2(hidden_states)) + return self.proj(hidden_states).squeeze(dim=2) + + +# Copied from transformers.models.seamless_m4t.modeling_seamless_m4t.SeamlessM4THifiGan with SeamlessM4T->SeamlessM4Tv2 +class SeamlessM4Tv2HifiGan(nn.Module): + def __init__(self, config: SeamlessM4Tv2Config): + super().__init__() + model_in_dim = config.unit_embed_dim + config.lang_embed_dim + config.spkr_embed_dim + self.leaky_relu_slope = config.leaky_relu_slope + self.num_kernels = len(config.resblock_kernel_sizes) + self.num_upsamples = len(config.upsample_rates) + self.conv_pre = nn.Conv1d( + model_in_dim, + config.upsample_initial_channel, + kernel_size=7, + stride=1, + padding=3, + ) + + self.upsampler = nn.ModuleList() + for i, (upsample_rate, kernel_size) in enumerate(zip(config.upsample_rates, config.upsample_kernel_sizes)): + self.upsampler.append( + nn.ConvTranspose1d( + config.upsample_initial_channel // (2**i), + config.upsample_initial_channel // (2 ** (i + 1)), + kernel_size=kernel_size, + stride=upsample_rate, + padding=(kernel_size - upsample_rate) // 2, + ) + ) + + self.resblocks = nn.ModuleList() + for i in range(len(self.upsampler)): + channels = config.upsample_initial_channel // (2 ** (i + 1)) + for kernel_size, dilation in zip(config.resblock_kernel_sizes, config.resblock_dilation_sizes): + self.resblocks.append(HifiGanResidualBlock(channels, kernel_size, dilation, config.leaky_relu_slope)) + + self.conv_post = nn.Conv1d(channels, 1, kernel_size=7, stride=1, padding=3) + + @deprecate_kwarg("input_embeds", version="5.6.0", new_name="inputs_embeds") + def forward(self, inputs_embeds: torch.FloatTensor) -> torch.FloatTensor: + r""" + Converts a log-mel spectrogram into a speech waveform. Passing a batch of log-mel spectrograms returns a batch + of speech waveforms. Passing a single, un-batched log-mel spectrogram returns a single, un-batched speech + waveform. + + Args: + spectrogram (`torch.FloatTensor`): + Tensor containing the log-mel spectrograms. Can be batched and of shape `(batch_size, sequence_length, + model_in_dim)`, or un-batched and of shape `(sequence_length, model_in_dim)`. Note that `model_in_dim` + is the sum of `config.unit_embed_dim`, `config.lang_embed_dim` and `config.spkr_embed_dim`. + + Returns: + `torch.FloatTensor`: Tensor containing the speech waveform. If the input spectrogram is batched, will be of + shape `(batch_size, num_frames,)`. If un-batched, will be of shape `(num_frames,)`. + """ + + hidden_states = self.conv_pre(inputs_embeds) + for i in range(self.num_upsamples): + hidden_states = nn.functional.leaky_relu(hidden_states, self.leaky_relu_slope) + hidden_states = self.upsampler[i](hidden_states) + + res_state = self.resblocks[i * self.num_kernels](hidden_states) + for j in range(1, self.num_kernels): + res_state += self.resblocks[i * self.num_kernels + j](hidden_states) + hidden_states = res_state / self.num_kernels + + hidden_states = nn.functional.leaky_relu(hidden_states) + hidden_states = self.conv_post(hidden_states) + hidden_states = torch.tanh(hidden_states) + + # remove seq-len dim since this collapses to 1 + waveform = hidden_states.squeeze(1) + + return waveform + + +@auto_docstring( + custom_intro=""" + Code HiFi-GAN vocoder as described in this [repository](https://github.com/facebookresearch/speech-resynthesis). + """ +) +class SeamlessM4Tv2CodeHifiGan(PreTrainedModel): + config: SeamlessM4Tv2Config + main_input_name = "inputs_embeds" + input_modalities = "audio" + _no_split_modules = [] + + def __init__(self, config): + super().__init__(config) + + self.pad_token_id = config.t2u_pad_token_id + embed_dim = config.unit_embed_dim + kernel_size = config.variance_predictor_kernel_size + var_pred_dropout = config.var_pred_dropout + self.dur_predictor = SeamlessM4Tv2VariancePredictor(embed_dim, embed_dim, kernel_size, var_pred_dropout) + + self.unit_embedding = nn.Embedding(config.unit_hifi_gan_vocab_size, config.unit_embed_dim) + self.speaker_embedding = nn.Embedding(config.vocoder_num_spkrs, config.spkr_embed_dim) + self.language_embedding = nn.Embedding(config.vocoder_num_langs, config.lang_embed_dim) + + self.hifi_gan = SeamlessM4Tv2HifiGan(config) + + # Initialize weights and apply final processing + self.post_init() + + # Copied from transformers.models.seamless_m4t.modeling_seamless_m4t.SeamlessM4TCodeHifiGan._get_dur_output_lengths + def _get_dur_output_lengths(self, input_ids, dur_out): + """ + Computes the output length after the duration layer. + """ + unit_lengths = (input_ids != self.pad_token_id).sum(1) + + # take care of edge cases where no padding or too many padding + unit_lengths = torch.clamp(unit_lengths, 0, dur_out.shape[1] - 1) + + cumulative_dur_out = torch.cumsum(dur_out, dim=1) + unit_lengths = cumulative_dur_out.gather(dim=1, index=unit_lengths.unsqueeze(1)).squeeze() + + return unit_lengths + + # Copied from transformers.models.seamless_m4t.modeling_seamless_m4t.SeamlessM4TCodeHifiGan._get_output_hifigan_lengths + def _get_output_hifigan_lengths(self, input_lengths: torch.LongTensor | int): + """ + Computes the output length of the hifigan convolutional layers + """ + + def _conv_out_length(input_length, kernel_size, stride, pad, dilation=1): + # 1D convolutional layer output length formula taken + # from https://pytorch.org/docs/stable/generated/torch.nn.Conv1d.html + return ( + torch.div(input_length + 2 * pad - dilation * (kernel_size - 1) - 1, stride, rounding_mode="floor") + 1 + ) + + def _transpose_conv_out_length(input_length, kernel_size, stride, pad, dilation=1): + return (input_length - 1) * stride - 2 * pad + dilation * (kernel_size - 1) + 1 + + # conv_pre + input_lengths = _conv_out_length(input_lengths, 7, 1, 3) + + # upsampler + for i, (upsample_rate, kernel_size) in enumerate( + zip(self.config.upsample_rates, self.config.upsample_kernel_sizes) + ): + input_lengths = _transpose_conv_out_length( + input_lengths, kernel_size, upsample_rate, (kernel_size - upsample_rate) // 2 + ) + + # resblock + for i in range(len(self.config.upsample_rates)): + for kernel_size, dilation in zip(self.config.resblock_kernel_sizes, self.config.resblock_dilation_sizes): + for dil in dilation: + input_lengths = _conv_out_length( + input_lengths, kernel_size, 1, (kernel_size - 1) * dil // 2, dilation=dil + ) + + for dil in dilation: + input_lengths = _conv_out_length(input_lengths, kernel_size, 1, (kernel_size - 1) // 2, dilation=1) + + # conv_post + input_lengths = _conv_out_length(input_lengths, 7, 1, 3) + + return input_lengths + + # Copied from transformers.models.seamless_m4t.modeling_seamless_m4t.SeamlessM4TCodeHifiGan.forward with SeamlessM4T->SeamlessM4Tv2, spkr_id->speaker_id + def forward( + self, input_ids: torch.LongTensor, speaker_id: torch.Tensor, lang_id: torch.Tensor, **kwargs + ) -> tuple[torch.Tensor]: + """ + Args: + input_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`): + Indices of input sequence tokens in the vocabulary. + + Indices can be obtained using [`SeamlessM4Tv2TextToUnitForConditionalGeneration`]. [What are input + IDs?](../glossary#input-ids) + speaker_id (`int`, *optional*): + The id of the speaker used for speech synthesis. Must be lower than `config.vocoder_num_spkrs`. + tgt_lang (`str`, *optional*): + The language id to use as target language for translation. + """ + hidden_states = self.unit_embedding(input_ids).transpose(1, 2) + spkr = self.speaker_embedding(speaker_id).transpose(1, 2) + lang = self.language_embedding(lang_id).transpose(1, 2) + + log_dur_pred = self.dur_predictor(hidden_states.transpose(1, 2)) + dur_out = torch.clamp(torch.round(torch.expm1(log_dur_pred)).long(), min=1) + # B x C x T + if hidden_states.size(0) == 1: + hidden_states = torch.repeat_interleave(hidden_states, dur_out.view(-1), dim=2) + else: + # if batched sample, need to interleave per sample, and pad -> loss of parallelism + if hidden_states.shape[0] > 1 and self.training: + logger.warning( + """`self.training=True` and you use batching. You lose parallelism during the hifigan + forward pass because the samples are interleaved.""" + ) + hidden_states = [ + torch.repeat_interleave(hidden_state, duration, dim=-1).transpose(0, 1) + for (hidden_state, duration) in zip(hidden_states, dur_out) + ] + + hidden_states = nn.utils.rnn.pad_sequence(hidden_states, batch_first=True).transpose(1, 2) + + spkr = spkr.repeat(1, 1, hidden_states.shape[-1]) + lang = lang.repeat(1, 1, hidden_states.shape[-1]) + hidden_states = torch.cat([lang, hidden_states, spkr], dim=1) + + hidden_states = self.hifi_gan(hidden_states) + + unit_lengths = self._get_dur_output_lengths(input_ids, dur_out) + lengths = self._get_output_hifigan_lengths(unit_lengths) + + return hidden_states, lengths + + # Copied from transformers.models.seamless_m4t.modeling_seamless_m4t.SeamlessM4TCodeHifiGan.apply_weight_norm + def apply_weight_norm(self): + weight_norm = nn.utils.weight_norm + if hasattr(nn.utils.parametrizations, "weight_norm"): + weight_norm = nn.utils.parametrizations.weight_norm + + weight_norm(self.hifi_gan.conv_pre) + for layer in self.hifi_gan.upsampler: + weight_norm(layer) + for layer in self.hifi_gan.resblocks: + layer.apply_weight_norm() + weight_norm(self.hifi_gan.conv_post) + + # Copied from transformers.models.seamless_m4t.modeling_seamless_m4t.SeamlessM4TCodeHifiGan.remove_weight_norm + def remove_weight_norm(self): + nn.utils.remove_weight_norm(self.hifi_gan.conv_pre) + for layer in self.hifi_gan.upsampler: + nn.utils.remove_weight_norm(layer) + for layer in self.hifi_gan.resblocks: + layer.remove_weight_norm() + nn.utils.remove_weight_norm(self.hifi_gan.conv_post) + + +############ WHOLE MODEL related code ################ + + +@auto_docstring( + custom_intro=""" + The text-to-text SeamlessM4Tv2 Model transformer which can be used for T2TT. + """ +) +# Copied from transformers.models.seamless_m4t.modeling_seamless_m4t.SeamlessM4TForTextToText with SeamlessM4T->SeamlessM4Tv2,SeamlessM4Tv2Tokenizer->SeamlessM4TTokenizer, SeamlessM4Tv2Processor->SeamlessM4TProcessor, SEAMLESS_M4T->SEAMLESS_M4T_V2 +class SeamlessM4Tv2ForTextToText(SeamlessM4Tv2PreTrainedModel, GenerationMixin): + _keys_to_ignore_on_load_missing = ["speech_encoder", "t2u_model", "vocoder"] + main_input_name = "input_ids" + + _tied_weights_keys = { + "lm_head.weight": "shared.weight", + "text_encoder.embed_tokens.weight": "shared.weight", + "text_decoder.embed_tokens.weight": "shared.weight", + } + + def __init__(self, config: SeamlessM4Tv2Config): + super().__init__(config) + + self.shared = nn.Embedding(config.vocab_size, config.hidden_size, config.pad_token_id) + + self.text_encoder = SeamlessM4Tv2Encoder(config) + self.text_decoder = SeamlessM4Tv2Decoder(config) + self.lm_head = nn.Linear(config.hidden_size, config.vocab_size, bias=False) + + # Initialize weights and apply final processing + self.post_init() + + def get_encoder(self): + return self.text_encoder + + def get_decoder(self): + return self.text_decoder + + def get_input_embeddings(self): + return self.text_decoder.embed_tokens + + def set_input_embeddings(self, value): + self.text_encoder.embed_tokens = value + self.text_decoder.embed_tokens = value + self.shared = value + + @auto_docstring(custom_args=SEAMLESS_M4T_V2_COMMON_CUSTOM_ARGS) + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.Tensor | None = None, + decoder_input_ids: torch.LongTensor | None = None, + decoder_attention_mask: torch.LongTensor | None = None, + encoder_outputs: tuple[tuple[torch.FloatTensor]] | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.FloatTensor | None = None, + decoder_inputs_embeds: torch.FloatTensor | None = None, + labels: torch.LongTensor | None = None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + **kwargs, + ) -> Seq2SeqLMOutput | tuple[torch.FloatTensor]: + r""" + labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Labels for computing the masked language modeling loss. Indices should be in `[-100, 0, ..., + config.vocab_size]` (see `input_ids` docstring) Tokens with indices set to `-100` are ignored (masked), the + loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]` + """ + if labels is not None: + if use_cache: + logger.warning("The `use_cache` argument is changed to `False` since `labels` is provided.") + use_cache = False + if decoder_input_ids is None and decoder_inputs_embeds is None: + decoder_input_ids = shift_tokens_right( + labels, self.config.pad_token_id, self.config.decoder_start_token_id + ) + + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + use_cache = use_cache if use_cache is not None else self.config.use_cache + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + if encoder_outputs is None: + encoder_outputs = self.text_encoder( + input_ids=input_ids, + attention_mask=attention_mask, + inputs_embeds=inputs_embeds, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + # If the user passed a tuple for encoder_outputs, we wrap it in a BaseModelOutput when return_dict=True + elif return_dict and not isinstance(encoder_outputs, BaseModelOutput): + encoder_outputs = BaseModelOutput( + last_hidden_state=encoder_outputs[0], + hidden_states=encoder_outputs[1] if len(encoder_outputs) > 1 else None, + attentions=encoder_outputs[2] if len(encoder_outputs) > 2 else None, + ) + + encoder_attention_mask = attention_mask + + # decoder outputs consists of (dec_features, past_key_values, dec_hidden, dec_attn) + decoder_outputs = self.text_decoder( + input_ids=decoder_input_ids, + attention_mask=decoder_attention_mask, + encoder_hidden_states=encoder_outputs[0], + encoder_attention_mask=encoder_attention_mask, + past_key_values=past_key_values, + inputs_embeds=decoder_inputs_embeds, + use_cache=use_cache, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + + lm_logits = self.lm_head(decoder_outputs[0]) + + masked_lm_loss = None + if labels is not None: + loss_fct = CrossEntropyLoss() + labels = labels.to(lm_logits.device) + masked_lm_loss = loss_fct(lm_logits.view(-1, self.config.vocab_size), labels.view(-1)) + + if not return_dict: + outputs = decoder_outputs + encoder_outputs + output = (lm_logits,) + outputs[1:] + return ((masked_lm_loss,) + output) if masked_lm_loss is not None else output + + return Seq2SeqLMOutput( + loss=masked_lm_loss, + logits=lm_logits, + past_key_values=decoder_outputs.past_key_values, + decoder_hidden_states=decoder_outputs.hidden_states, + decoder_attentions=decoder_outputs.attentions, + cross_attentions=decoder_outputs.cross_attentions, + encoder_last_hidden_state=encoder_outputs.last_hidden_state, + encoder_hidden_states=encoder_outputs.hidden_states, + encoder_attentions=encoder_outputs.attentions, + ) + + def generate( + self, + input_ids=None, + tgt_lang=None, + generation_config=None, + logits_processor=None, + stopping_criteria=None, + prefix_allowed_tokens_fn=None, + synced_gpus=False, + **kwargs, + ): + """ + Generates sequences of token ids. + + + + Most generation-controlling parameters are set in `generation_config` which, if not passed, will be set to the + model's default generation configuration. You can override any `generation_config` by passing the corresponding + parameters to generate(), e.g. `.generate(inputs, num_beams=4, do_sample=True)`. + + For an overview of generation strategies and code examples, check out the [following + guide](./generation_strategies). + + + + Parameters: + input_ids (`torch.Tensor` of varying shape depending on the modality, *optional*): + Indices of input sequence tokens in the vocabulary. + + Indices can be obtained using [`SeamlessM4TTokenizer`] or [`SeamlessM4TProcessor`]. See + [`PreTrainedTokenizer.encode`] and [`PreTrainedTokenizer.__call__`] for details. + + [What are input IDs?](../glossary#input-ids) + tgt_lang (`str`, *optional*): + The language to use as target language for translation. + generation_config (`~generation.GenerationConfig`, *optional*): + The generation configuration to be used as base parametrization for the generation call. `**kwargs` + passed to generate matching the attributes of `generation_config` will override them. If + `generation_config` is not provided, the default will be used, which had the following loading + priority: 1) from the `generation_config.json` model file, if it exists; 2) from the model + configuration. Please note that unspecified parameters will inherit [`~generation.GenerationConfig`]'s + default values, whose documentation should be checked to parameterize generation. + logits_processor (`LogitsProcessorList`, *optional*): + Custom logits processors that complement the default logits processors built from arguments and + generation config. If a logit processor is passed that is already created with the arguments or a + generation config an error is thrown. This feature is intended for advanced users. + stopping_criteria (`StoppingCriteriaList`, *optional*): + Custom stopping criteria that complement the default stopping criteria built from arguments and a + generation config. If a stopping criteria is passed that is already created with the arguments or a + generation config an error is thrown. This feature is intended for advanced users. + prefix_allowed_tokens_fn (`Callable[[int, torch.Tensor], list[int]]`, *optional*): + If provided, this function constraints the beam search to allowed tokens only at each step. If not + provided no constraint is applied. This function takes 2 arguments: the batch ID `batch_id` and + `input_ids`. It has to return a list with the allowed tokens for the next generation step conditioned + on the batch ID `batch_id` and the previously generated tokens `inputs_ids`. This argument is useful + for constrained generation conditioned on the prefix, as described in [Autoregressive Entity + Retrieval](https://huggingface.co/papers/2010.00904). + synced_gpus (`bool`, *optional*, defaults to `False`): + Whether to continue running the while loop until max_length (needed to avoid deadlocking with + `FullyShardedDataParallel` and DeepSpeed ZeRO Stage 3). + kwargs (`dict[str, Any]`, *optional*): + Ad hoc parametrization of `generate_config` and/or additional model-specific kwargs that will be + forwarded to the `forward` function of the model. + + Return: + [`~utils.ModelOutput`] or `torch.LongTensor`: A [`~utils.ModelOutput`] (if `return_dict_in_generate=True` + or when `config.return_dict_in_generate=True`) or a `torch.FloatTensor`. The possible + [`~utils.ModelOutput`] types are: + - [`~generation.GenerateEncoderDecoderOutput`], + - [`~generation.GenerateBeamEncoderDecoderOutput`] + """ + # prepare text_decoder_input_ids + text_decoder_input_ids = kwargs.pop("decoder_input_ids", None) + # overwrite text_decoder_input_ids if tgt_lang is passed. The latter gets priority over decoder_input_ids. + if tgt_lang is not None: + batch_size = len(input_ids) if input_ids is not None else len(kwargs.get("inputs_embeds")) + + if hasattr(self.generation_config, "text_decoder_lang_to_code_id"): + # also accept __xxx__ + tgt_lang = tgt_lang.replace("__", "") + if tgt_lang not in self.generation_config.text_decoder_lang_to_code_id: + raise ValueError( + f"""`tgt_lang={tgt_lang}` is not supported by this model. Please specify a `tgt_lang` in + {", ".join(self.generation_config.text_decoder_lang_to_code_id.keys())}""" + ) + # tgt_lang gets priority over decoder input ids + text_tgt_lang_id = self.generation_config.text_decoder_lang_to_code_id.get(tgt_lang) + text_decoder_input_ids = torch.tensor([[text_tgt_lang_id]] * batch_size, device=self.device) + else: + raise ValueError( + """This model generation config doesn't have a `text_decoder_lang_to_code_id` key which maps + the target language to the right token id. Make sure to load the right generation config.""" + ) + else: + # only a warning, otherwise errors appear in the tests + logger.warning( + """You must either specify a `tgt_lang` or pass a correct `text_decoder_input_ids` to get + a correct generation, otherwise the generation will probably make no sense.""" + ) + + return super().generate( + input_ids, + generation_config, + logits_processor, + stopping_criteria, + prefix_allowed_tokens_fn, + synced_gpus, + decoder_input_ids=text_decoder_input_ids, + **kwargs, + ) + + +@auto_docstring( + custom_intro=""" + The speech-to-text SeamlessM4Tv2 Model transformer which can be used for S2TT. + """ +) +class SeamlessM4Tv2ForSpeechToText(SeamlessM4Tv2PreTrainedModel, GenerationMixin): + input_modalities = "audio" + _keys_to_ignore_on_load_missing = ["text_encoder", "t2u_model", "vocoder"] + main_input_name = "input_features" + + _tied_weights_keys = { + "lm_head.weight": "shared.weight", + "text_decoder.embed_tokens.weight": "shared.weight", + } + + # Copied from transformers.models.seamless_m4t.modeling_seamless_m4t.SeamlessM4TForSpeechToText.__init__ with SeamlessM4T->SeamlessM4Tv2 + def __init__(self, config: SeamlessM4Tv2Config): + super().__init__(config) + + self.shared = nn.Embedding(config.vocab_size, config.hidden_size, config.pad_token_id) + self.speech_encoder = SeamlessM4Tv2SpeechEncoder(config) + self.text_decoder = SeamlessM4Tv2Decoder(config) + self.lm_head = nn.Linear(config.hidden_size, config.vocab_size, bias=False) + + # Initialize weights and apply final processing + self.post_init() + + # Copied from transformers.models.seamless_m4t.modeling_seamless_m4t.SeamlessM4TForSpeechToText.get_encoder + def get_encoder(self): + return self.speech_encoder + + # Copied from transformers.models.seamless_m4t.modeling_seamless_m4t.SeamlessM4TForSpeechToText.get_decoder + def get_decoder(self): + return self.text_decoder + + # Copied from transformers.models.seamless_m4t.modeling_seamless_m4t.SeamlessM4TForSpeechToText.get_input_embeddings + def get_input_embeddings(self): + return self.text_decoder.embed_tokens + + # Copied from transformers.models.seamless_m4t.modeling_seamless_m4t.SeamlessM4TForSpeechToText.set_input_embeddings + def set_input_embeddings(self, value): + self.text_decoder.embed_tokens = value + + @auto_docstring(custom_args=SEAMLESS_M4T_V2_COMMON_CUSTOM_ARGS) + # Copied from transformers.models.seamless_m4t.modeling_seamless_m4t.SeamlessM4TForSpeechToText.forward + def forward( + self, + input_features: torch.LongTensor | None = None, + attention_mask: torch.Tensor | None = None, + decoder_input_ids: torch.LongTensor | None = None, + decoder_attention_mask: torch.LongTensor | None = None, + encoder_outputs: tuple[tuple[torch.FloatTensor]] | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.FloatTensor | None = None, + decoder_inputs_embeds: torch.FloatTensor | None = None, + labels: torch.LongTensor | None = None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + **kwargs, + ) -> Seq2SeqLMOutput | tuple[torch.FloatTensor]: + r""" + labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Labels for computing the masked language modeling loss. Indices should be in `[-100, 0, ..., + config.vocab_size]` (see `input_ids` docstring) Tokens with indices set to `-100` are ignored (masked), the + loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]` + """ + if labels is not None: + if use_cache: + logger.warning("The `use_cache` argument is changed to `False` since `labels` is provided.") + use_cache = False + if decoder_input_ids is None and decoder_inputs_embeds is None: + decoder_input_ids = shift_tokens_right( + labels, self.config.pad_token_id, self.config.decoder_start_token_id + ) + + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + use_cache = use_cache if use_cache is not None else self.config.use_cache + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + if encoder_outputs is None: + encoder_outputs = self.speech_encoder( + input_features=input_features, + attention_mask=attention_mask, + inputs_embeds=inputs_embeds, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + # If the user passed a tuple for encoder_outputs, we wrap it in a BaseModelOutput when return_dict=True + elif return_dict and not isinstance(encoder_outputs, BaseModelOutput): + encoder_outputs = BaseModelOutput( + last_hidden_state=encoder_outputs[0], + hidden_states=encoder_outputs[1] if len(encoder_outputs) > 1 else None, + attentions=encoder_outputs[2] if len(encoder_outputs) > 2 else None, + ) + + encoder_attention_mask = attention_mask + if attention_mask is not None: + sub_sampled_lengths = self._compute_sub_sample_lengths_from_attention_mask(attention_mask).to( + encoder_outputs[0].device + ) + encoder_attention_mask = _compute_new_attention_mask( + hidden_states=encoder_outputs[0], seq_lens=sub_sampled_lengths + ) + + # decoder outputs consists of (dec_features, past_key_values, dec_hidden, dec_attn) + decoder_outputs = self.text_decoder( + input_ids=decoder_input_ids, + attention_mask=decoder_attention_mask, + encoder_hidden_states=encoder_outputs[0], + encoder_attention_mask=encoder_attention_mask, + past_key_values=past_key_values, + inputs_embeds=decoder_inputs_embeds, + use_cache=use_cache, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + + lm_logits = self.lm_head(decoder_outputs[0]) + + masked_lm_loss = None + if labels is not None: + loss_fct = CrossEntropyLoss() + labels = labels.to(lm_logits.device) + masked_lm_loss = loss_fct(lm_logits.view(-1, self.config.vocab_size), labels.view(-1)) + + if not return_dict: + outputs = decoder_outputs + encoder_outputs + output = (lm_logits,) + outputs[1:] + return ((masked_lm_loss,) + output) if masked_lm_loss is not None else output + + return Seq2SeqLMOutput( + loss=masked_lm_loss, + logits=lm_logits, + past_key_values=decoder_outputs.past_key_values, + decoder_hidden_states=decoder_outputs.hidden_states, + decoder_attentions=decoder_outputs.attentions, + cross_attentions=decoder_outputs.cross_attentions, + encoder_last_hidden_state=encoder_outputs.last_hidden_state, + encoder_hidden_states=encoder_outputs.hidden_states, + encoder_attentions=encoder_outputs.attentions, + ) + + # Copied from transformers.models.seamless_m4t.modeling_seamless_m4t.SeamlessM4TForSpeechToText.generate + def generate( + self, + input_features=None, + tgt_lang=None, + generation_config=None, + logits_processor=None, + stopping_criteria=None, + prefix_allowed_tokens_fn=None, + synced_gpus=False, + **kwargs, + ): + """ + Generates sequences of token ids. + + + + Most generation-controlling parameters are set in `generation_config` which, if not passed, will be set to the + model's default generation configuration. You can override any `generation_config` by passing the corresponding + parameters to generate(), e.g. `.generate(inputs, num_beams=4, do_sample=True)`. + + For an overview of generation strategies and code examples, check out the [following + guide](./generation_strategies). + + + + Parameters: + input_features (`torch.FloatTensor` of shape `(batch_size, sequence_length, num_banks)`): + Input audio features. This should be returned by the [`SeamlessM4TFeatureExtractor`] class or the + [`SeamlessM4TProcessor`] class. See [`SeamlessM4TFeatureExtractor.__call__`] for details. + + tgt_lang (`str`, *optional*): + The language to use as target language for translation. + generation_config (`~generation.GenerationConfig`, *optional*): + The generation configuration to be used as base parametrization for the generation call. `**kwargs` + passed to generate matching the attributes of `generation_config` will override them. If + `generation_config` is not provided, the default will be used, which had the following loading + priority: 1) from the `generation_config.json` model file, if it exists; 2) from the model + configuration. Please note that unspecified parameters will inherit [`~generation.GenerationConfig`]'s + default values, whose documentation should be checked to parameterize generation. + logits_processor (`LogitsProcessorList`, *optional*): + Custom logits processors that complement the default logits processors built from arguments and + generation config. If a logit processor is passed that is already created with the arguments or a + generation config an error is thrown. This feature is intended for advanced users. + stopping_criteria (`StoppingCriteriaList`, *optional*): + Custom stopping criteria that complement the default stopping criteria built from arguments and a + generation config. If a stopping criteria is passed that is already created with the arguments or a + generation config an error is thrown. This feature is intended for advanced users. + prefix_allowed_tokens_fn (`Callable[[int, torch.Tensor], list[int]]`, *optional*): + If provided, this function constraints the beam search to allowed tokens only at each step. If not + provided no constraint is applied. This function takes 2 arguments: the batch ID `batch_id` and + `input_ids`. It has to return a list with the allowed tokens for the next generation step conditioned + on the batch ID `batch_id` and the previously generated tokens `inputs_ids`. This argument is useful + for constrained generation conditioned on the prefix, as described in [Autoregressive Entity + Retrieval](https://huggingface.co/papers/2010.00904). + synced_gpus (`bool`, *optional*, defaults to `False`): + Whether to continue running the while loop until max_length (needed to avoid deadlocking with + `FullyShardedDataParallel` and DeepSpeed ZeRO Stage 3). + kwargs (`dict[str, Any]`, *optional*): + Ad hoc parametrization of `generate_config` and/or additional model-specific kwargs that will be + forwarded to the `forward` function of the model. + + Return: + [`~utils.ModelOutput`] or `torch.LongTensor`: A [`~utils.ModelOutput`] (if `return_dict_in_generate=True` + or when `config.return_dict_in_generate=True`) or a `torch.FloatTensor`. The possible + [`~utils.ModelOutput`] types are: + - [`~generation.GenerateEncoderDecoderOutput`], + - [`~generation.GenerateBeamEncoderDecoderOutput`] + """ + text_decoder_input_ids = kwargs.pop("decoder_input_ids", None) + # overwrite text_decoder_input_ids if tgt_lang is passed. The latter gets priority over decoder_input_ids. + input_features = input_features if input_features is not None else kwargs.pop("inputs") + if tgt_lang is not None: + inputs = kwargs.get("inputs_embeds") if input_features is None else input_features + inputs = ( + inputs + if inputs is not None + else kwargs.get("encoder_outputs", {"last_hidden_state": None})["last_hidden_state"] + ) + batch_size = len(inputs) + + if hasattr(self.generation_config, "text_decoder_lang_to_code_id"): + # also accept __xxx__ + tgt_lang = tgt_lang.replace("__", "") + if tgt_lang not in self.generation_config.text_decoder_lang_to_code_id: + raise ValueError( + f"""`tgt_lang={tgt_lang}` is not supported by this model. Please specify a `tgt_lang` in + {", ".join(self.generation_config.text_decoder_lang_to_code_id.keys())}""" + ) + # tgt_lang gets priority over decoder input ids + text_tgt_lang_id = self.generation_config.text_decoder_lang_to_code_id.get(tgt_lang) + text_decoder_input_ids = torch.tensor([[text_tgt_lang_id]] * batch_size, device=self.device) + else: + raise ValueError( + """This model generation config doesn't have a `text_decoder_lang_to_code_id` key which maps + the target language to the right token id. Make sure to load the right generation config.""" + ) + else: + # only a warning, otherwise errors appear in the tests + logger.warning( + """You must either specify a `tgt_lang` or pass a correct `text_decoder_input_ids` to get + a correct generation, otherwise the generation will probably make no sense.""" + ) + return super().generate( + input_features, + generation_config, + logits_processor, + stopping_criteria, + prefix_allowed_tokens_fn, + synced_gpus, + decoder_input_ids=text_decoder_input_ids, + **kwargs, + ) + + +@auto_docstring( + custom_intro=""" + The text-to-speech SeamlessM4Tv2 Model transformer which can be used for T2ST. + """ +) +class SeamlessM4Tv2ForTextToSpeech(SeamlessM4Tv2PreTrainedModel, GenerationMixin): + output_modalities = ("audio",) + _keys_to_ignore_on_load_missing = ["speech_encoder"] + main_input_name = "input_ids" + + _tied_weights_keys = { + "lm_head.weight": "shared.weight", + "text_encoder.embed_tokens.weight": "shared.weight", + "text_decoder.embed_tokens.weight": "shared.weight", + } + + # Copied from transformers.models.seamless_m4t.modeling_seamless_m4t.SeamlessM4TForTextToSpeech.__init__ with SeamlessM4T->SeamlessM4Tv2 + def __init__(self, config: SeamlessM4Tv2Config): + super().__init__(config) + + self.shared = nn.Embedding(config.vocab_size, config.hidden_size, config.pad_token_id) + + self.text_encoder = SeamlessM4Tv2Encoder(config) + self.text_decoder = SeamlessM4Tv2Decoder(config) + self.lm_head = nn.Linear(config.hidden_size, config.vocab_size, bias=False) + + self.t2u_model = SeamlessM4Tv2TextToUnitForConditionalGeneration(config) + self.vocoder = SeamlessM4Tv2CodeHifiGan(config) + + # Initialize weights and apply final processing + self.post_init() + + # Copied from transformers.models.seamless_m4t.modeling_seamless_m4t.SeamlessM4TForTextToSpeech.get_encoder + def get_encoder(self): + return self.text_encoder + + # Copied from transformers.models.seamless_m4t.modeling_seamless_m4t.SeamlessM4TForTextToSpeech.get_decoder + def get_decoder(self): + return self.text_decoder + + # Copied from transformers.models.seamless_m4t.modeling_seamless_m4t.SeamlessM4TForTextToSpeech.get_input_embeddings + def get_input_embeddings(self): + return self.text_decoder.embed_tokens + + # Copied from transformers.models.seamless_m4t.modeling_seamless_m4t.SeamlessM4TForTextToSpeech.set_input_embeddings + def set_input_embeddings(self, value): + self.text_encoder.embed_tokens = value + self.text_decoder.embed_tokens = value + self.shared = value + + @auto_docstring(custom_args=SEAMLESS_M4T_V2_COMMON_CUSTOM_ARGS) + # Copied from transformers.models.seamless_m4t.modeling_seamless_m4t.SeamlessM4TForTextToSpeech.forward with SeamlessM4T->SeamlessM4Tv2 + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.Tensor | None = None, + decoder_input_ids: torch.LongTensor | None = None, + decoder_attention_mask: torch.LongTensor | None = None, + encoder_outputs: tuple[tuple[torch.FloatTensor]] | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.FloatTensor | None = None, + decoder_inputs_embeds: torch.FloatTensor | None = None, + labels: torch.LongTensor | None = None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + cache_position: torch.Tensor | None = None, + **kwargs, + ) -> Seq2SeqLMOutput | tuple[torch.FloatTensor]: + r""" + labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Labels for computing the masked language modeling loss. Indices should be in `[-100, 0, ..., + config.vocab_size]` (see `input_ids` docstring) Tokens with indices set to `-100` are ignored (masked), the + loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]` + """ + if labels is not None: + if use_cache: + logger.warning("The `use_cache` argument is changed to `False` since `labels` is provided.") + use_cache = False + if decoder_input_ids is None and decoder_inputs_embeds is None: + decoder_input_ids = shift_tokens_right( + labels, self.config.pad_token_id, self.config.decoder_start_token_id + ) + + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + use_cache = use_cache if use_cache is not None else self.config.use_cache + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + if encoder_outputs is None: + # if encoder_outputs is not None, it's probably used within a .generate method so no need to warn + logger.warning( + "This is the same forward method as `SeamlessM4Tv2ForTextToText`." + "It doesn't use the text-to-unit model `SeamlessM4Tv2TextToUnitForConditionalGeneration`." + "If you want to generate speech, use the `.generate` method." + ) + encoder_outputs = self.text_encoder( + input_ids=input_ids, + attention_mask=attention_mask, + inputs_embeds=inputs_embeds, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + # If the user passed a tuple for encoder_outputs, we wrap it in a BaseModelOutput when return_dict=True + elif return_dict and not isinstance(encoder_outputs, BaseModelOutput): + encoder_outputs = BaseModelOutput( + last_hidden_state=encoder_outputs[0], + hidden_states=encoder_outputs[1] if len(encoder_outputs) > 1 else None, + attentions=encoder_outputs[2] if len(encoder_outputs) > 2 else None, + ) + + encoder_attention_mask = attention_mask + + # decoder outputs consists of (dec_features, past_key_values, dec_hidden, dec_attn) + decoder_outputs = self.text_decoder( + input_ids=decoder_input_ids, + attention_mask=decoder_attention_mask, + encoder_hidden_states=encoder_outputs[0], + encoder_attention_mask=encoder_attention_mask, + past_key_values=past_key_values, + inputs_embeds=decoder_inputs_embeds, + use_cache=use_cache, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + cache_position=cache_position, + ) + + lm_logits = self.lm_head(decoder_outputs[0]) + + masked_lm_loss = None + if labels is not None: + loss_fct = CrossEntropyLoss() + labels = labels.to(lm_logits.device) + masked_lm_loss = loss_fct(lm_logits.view(-1, self.config.vocab_size), labels.view(-1)) + + if not return_dict: + outputs = decoder_outputs + encoder_outputs + output = (lm_logits,) + outputs[1:] + return ((masked_lm_loss,) + output) if masked_lm_loss is not None else output + + return Seq2SeqLMOutput( + loss=masked_lm_loss, + logits=lm_logits, + past_key_values=decoder_outputs.past_key_values, + decoder_hidden_states=decoder_outputs.hidden_states, + decoder_attentions=decoder_outputs.attentions, + cross_attentions=decoder_outputs.cross_attentions, + encoder_last_hidden_state=encoder_outputs.last_hidden_state, + encoder_hidden_states=encoder_outputs.hidden_states, + encoder_attentions=encoder_outputs.attentions, + ) + + @torch.no_grad() + def generate( + self, + input_ids: torch.Tensor | None = None, + return_intermediate_token_ids: bool | None = None, + tgt_lang: str | None = None, + speaker_id: int | None = 0, + **kwargs, + ) -> torch.Tensor | SeamlessM4Tv2GenerationOutput: + """ + Generates translated audio waveforms. + + + + This method successively calls the `.generate` function of two different sub-models. You can specify keyword + arguments at two different levels: general arguments that will be passed to both models, or prefixed arguments + that will be passed to one of them. + + For example, calling `.generate(input_ids, num_beams=4, speech_do_sample=True)` will successively perform + beam-search decoding on the text model, and multinomial beam-search sampling on the speech model. + + For an overview of generation strategies and code examples, check out the [following + guide](./generation_strategies). + + + + Args: + input_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`): + Indices of input sequence tokens in the vocabulary. + + Indices can be obtained using [`SeamlessM4TTokenizer`] or [`SeamlessM4TProcessor`]. See + [`PreTrainedTokenizer.encode`] and [`PreTrainedTokenizer.__call__`] for details. + + [What are input IDs?](../glossary#input-ids) + return_intermediate_token_ids (`bool`, *optional*): + If `True`, also returns the intermediate generated text and unit tokens. Set to `True` if you also want + to get translated text alongside the audio. + tgt_lang (`str`, *optional*): + The language to use as target language for translation. + speaker_id (`int`, *optional*, defaults to 0): + The id of the speaker used for speech synthesis. Must be lower than `config.vocoder_num_spkrs`. + kwargs (*optional*): + Remaining dictionary of keyword arguments that will be passed to [`GenerationMixin.generate`]. Keyword + arguments are of two types: + + - Without a prefix, they will be entered as `**kwargs` for the `generate` method of each sub-model, + except for `decoder_input_ids` which will only be passed through the text components. + - With a *text_* or *speech_* prefix, they will be input for the `generate` method of the + text model and speech model respectively. It has the priority over the keywords without a prefix. + + This means you can, for example, specify a generation strategy for one generation but not for the + other. + + + Returns: + `Union[SeamlessM4Tv2GenerationOutput, tuple[Tensor]]`: + - If `return_intermediate_token_ids`, returns [`SeamlessM4Tv2GenerationOutput`]. + - If not `return_intermediate_token_ids`, returns a tuple composed of waveforms of shape `(batch_size, + sequence_length)` and `waveform_lengths` which gives the length of each sample. + """ + batch_size = len(input_ids) if input_ids is not None else len(kwargs.get("inputs_embeds")) + + if tgt_lang is None: + raise ValueError("You must specify a `tgt_lang` to generate translated speech.") + else: + # also accept __xxx__ + tgt_lang = tgt_lang.replace("__", "") + for key in ["text_decoder_lang_to_code_id", "t2u_lang_code_to_id", "vocoder_lang_code_to_id"]: + lang_code_to_id = getattr(self.generation_config, key, None) + if lang_code_to_id is None: + raise ValueError( + f"""This model generation config doesn't have a `{key}` key which maps the target language + to the right token id. Make sure to load the right generation config.""" + ) + elif tgt_lang not in lang_code_to_id: + raise ValueError( + f"""`tgt_lang={tgt_lang}` is not supported by this model. + Please specify a `tgt_lang` in {",".join(lang_code_to_id.keys())}. Note that SeamlessM4Tv2 supports + more languages for text translation than for speech synthesis.""" + ) + + kwargs_text, kwargs_speech = format_speech_generation_kwargs(kwargs) + kwargs_text["output_hidden_states"] = True + kwargs_text["return_dict_in_generate"] = True + kwargs_text["output_scores"] = True + + text_decoder_input_ids = kwargs_text.get("decoder_input_ids") + + # overwrite text_decoder_input_ids if tgt_lang is passed. The latter gets priority over decoder_input_ids. + text_tgt_lang_id = self.generation_config.text_decoder_lang_to_code_id.get(tgt_lang) + text_decoder_input_ids = torch.tensor([[text_tgt_lang_id]] * batch_size, device=self.device) + + kwargs_text["decoder_input_ids"] = text_decoder_input_ids + + # first generation + text_generation_output = super().generate(input_ids, **kwargs_text) + sequences = text_generation_output.sequences + + # prepare second generation + num_return_sequences = len(sequences) // batch_size + attention_mask = kwargs_speech.get("attention_mask", kwargs_text.get("attention_mask", None)) + + if attention_mask is not None: + # repeat attention mask alongside batch dimension + attention_mask = torch.repeat_interleave(attention_mask, num_return_sequences, dim=0) + encoder_hidden_states = text_generation_output.encoder_hidden_states[-1] + + # repeat attention mask alongside batch dimension + encoder_hidden_states = torch.repeat_interleave(encoder_hidden_states, num_return_sequences, dim=0) + + # get decoder last hidden state - must do a pass through the text decoder + t2u_input_embeds = self.text_decoder( + input_ids=sequences[:, :-1], # Manually trim the final EOS token + encoder_hidden_states=encoder_hidden_states, + encoder_attention_mask=attention_mask, + ).last_hidden_state + + pad_token_id = self.generation_config.pad_token_id + + # Compute new attention mask + seq_lens = (sequences[:, :-1] != pad_token_id).int().sum(1) + t2u_model_attention_mask = _compute_new_attention_mask(t2u_input_embeds, seq_lens) + kwargs_speech["attention_mask"] = t2u_model_attention_mask + + # REMOVE EOS and lang_id + t2u_input_ids = sequences[:, 2:-1] + # replace every other EOS + t2u_input_ids = torch.masked_fill( + t2u_input_ids, t2u_input_ids == self.generation_config.eos_token_id, pad_token_id + ) + + # compute t2u_char_input_ids + t2u_subwords = self._indices_to_subwords(t2u_input_ids) + t2u_char_count_per_id = self._count_character_length_in_subword( + t2u_input_ids, t2u_subwords, pad_token_id=pad_token_id + ) + + # Add pads for lang, EOS tokens as per NLLB "source" tokenizer mode. + pad_zero = t2u_char_count_per_id.new_zeros((t2u_char_count_per_id.shape[0], 1)) + t2u_char_count_per_id = torch.cat([pad_zero, t2u_char_count_per_id, pad_zero], dim=1) + t2u_char_input_ids = self._get_char_input_ids( + t2u_input_ids, t2u_subwords, t2u_char_count_per_id, pad_token_id=pad_token_id + ) + + # second pass + t2u_output = self.t2u_model( + inputs_embeds=t2u_input_embeds, + char_input_ids=t2u_char_input_ids, + char_count_per_id=t2u_char_count_per_id, + **kwargs_speech, + ) + + t2u_logits = t2u_output[0] + padding_mask = t2u_output[1].bool() + + # The text-to-unit model is non auto-regressive. We keep the ability to use sampling with temperature + temperature = kwargs_speech.get("temperature", None) + if (temperature is None or temperature == 1.0) or not kwargs_speech.get("do_sample", False): + unit_ids = t2u_logits.argmax(dim=-1) + else: + t2u_logits = t2u_logits / temperature + # apply softmax + probs = nn.functional.softmax(t2u_logits, dim=-1) + # reshape to 2D: (batch_size, seq_len, t2u_vocab_size) -> (batch_size*seq_len, t2u_vocab_size) + probs = probs.reshape((-1, probs.shape[2])) + # multinomial then reshape : (batch_size*seq_len)-> (batch_size,seq_len) + unit_ids = torch.multinomial(probs, num_samples=1).view(t2u_logits.shape[0], -1) + + output_unit_ids = unit_ids.detach().clone() + + replace_mask = (unit_ids == self.config.t2u_eos_token_id) | (~padding_mask) + # replace eos per pad + unit_ids = unit_ids.masked_fill(replace_mask, self.config.t2u_pad_token_id) + + # offset of control symbols + unit_ids = torch.where( + unit_ids == self.config.t2u_pad_token_id, unit_ids, unit_ids - self.config.vocoder_offset + ) + + vocoder_tgt_lang_id = self.generation_config.vocoder_lang_code_to_id.get(tgt_lang) + vocoder_tgt_lang_id = torch.tensor([[vocoder_tgt_lang_id]] * len(unit_ids), device=self.device) + + speaker_id = torch.tensor([[speaker_id]] * len(unit_ids), device=self.device) + + waveform, waveform_lengths = self.vocoder( + input_ids=unit_ids, speaker_id=speaker_id, lang_id=vocoder_tgt_lang_id + ) + + if return_intermediate_token_ids: + return SeamlessM4Tv2GenerationOutput( + waveform=waveform, + waveform_lengths=waveform_lengths, + sequences=sequences, + unit_sequences=output_unit_ids, + ) + + return waveform, waveform_lengths + + +@auto_docstring( + custom_intro=""" + The speech-to-speech SeamlessM4Tv2 Model transformer which can be used for S2ST. + """ +) +class SeamlessM4Tv2ForSpeechToSpeech(SeamlessM4Tv2PreTrainedModel, GenerationMixin): + input_modalities = "audio" + output_modalities = ("audio",) + _keys_to_ignore_on_load_missing = ["text_encoder"] + main_input_name = "input_features" + + _tied_weights_keys = {"lm_head.weight": "shared.weight", "text_decoder.embed_tokens.weight": "shared.weight"} + + # Copied from transformers.models.seamless_m4t.modeling_seamless_m4t.SeamlessM4TForSpeechToSpeech.__init__ with SeamlessM4T->SeamlessM4Tv2 + def __init__(self, config): + super().__init__(config) + + self.shared = nn.Embedding(config.vocab_size, config.hidden_size, config.pad_token_id) + self.speech_encoder = SeamlessM4Tv2SpeechEncoder(config) + self.text_decoder = SeamlessM4Tv2Decoder(config) + self.lm_head = nn.Linear(config.hidden_size, config.vocab_size, bias=False) + + self.t2u_model = SeamlessM4Tv2TextToUnitForConditionalGeneration(config) + self.vocoder = SeamlessM4Tv2CodeHifiGan(config) + self.post_init() + + # Copied from transformers.models.seamless_m4t.modeling_seamless_m4t.SeamlessM4TForSpeechToSpeech.get_encoder + def get_encoder(self): + return self.speech_encoder + + # Copied from transformers.models.seamless_m4t.modeling_seamless_m4t.SeamlessM4TForSpeechToSpeech.get_decoder + def get_decoder(self): + return self.text_decoder + + # Copied from transformers.models.seamless_m4t.modeling_seamless_m4t.SeamlessM4TForSpeechToSpeech.get_input_embeddings + def get_input_embeddings(self): + return self.text_decoder.embed_tokens + + # Copied from transformers.models.seamless_m4t.modeling_seamless_m4t.SeamlessM4TForSpeechToSpeech.set_input_embeddings + def set_input_embeddings(self, value): + self.text_decoder.embed_tokens = value + + @auto_docstring(custom_args=SEAMLESS_M4T_V2_COMMON_CUSTOM_ARGS) + # Copied from transformers.models.seamless_m4t.modeling_seamless_m4t.SeamlessM4TForSpeechToSpeech.forward with SeamlessM4T->SeamlessM4Tv2 + def forward( + self, + input_features: torch.LongTensor | None = None, + attention_mask: torch.Tensor | None = None, + decoder_input_ids: torch.LongTensor | None = None, + decoder_attention_mask: torch.LongTensor | None = None, + encoder_outputs: tuple[tuple[torch.FloatTensor]] | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.FloatTensor | None = None, + decoder_inputs_embeds: torch.FloatTensor | None = None, + labels: torch.LongTensor | None = None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + **kwargs, + ) -> Seq2SeqLMOutput | tuple[torch.FloatTensor]: + r""" + labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Labels for computing the masked language modeling loss. Indices should be in `[-100, 0, ..., + config.vocab_size]` (see `input_ids` docstring) Tokens with indices set to `-100` are ignored (masked), the + loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]` + """ + if labels is not None: + if use_cache: + logger.warning("The `use_cache` argument is changed to `False` since `labels` is provided.") + use_cache = False + if decoder_input_ids is None and decoder_inputs_embeds is None: + decoder_input_ids = shift_tokens_right( + labels, self.config.pad_token_id, self.config.decoder_start_token_id + ) + + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + use_cache = use_cache if use_cache is not None else self.config.use_cache + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + if encoder_outputs is None: + # if encoder_outputs is not None, it's probably used within a .generate method so no need to warn + logger.warning( + "This is the same forward method as `SeamlessM4Tv2ForSpeechToText`. It doesn't use `self.t2u_model`." + "If you want to generate speech, use the `generate` method." + ) + + encoder_outputs = self.speech_encoder( + input_features=input_features, + attention_mask=attention_mask, + inputs_embeds=inputs_embeds, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + # If the user passed a tuple for encoder_outputs, we wrap it in a BaseModelOutput when return_dict=True + elif return_dict and not isinstance(encoder_outputs, BaseModelOutput): + encoder_outputs = BaseModelOutput( + last_hidden_state=encoder_outputs[0], + hidden_states=encoder_outputs[1] if len(encoder_outputs) > 1 else None, + attentions=encoder_outputs[2] if len(encoder_outputs) > 2 else None, + ) + + encoder_attention_mask = attention_mask + if attention_mask is not None: + sub_sampled_lengths = self._compute_sub_sample_lengths_from_attention_mask(attention_mask).to( + encoder_outputs[0].device + ) + encoder_attention_mask = _compute_new_attention_mask( + hidden_states=encoder_outputs[0], seq_lens=sub_sampled_lengths + ) + + # decoder outputs consists of (dec_features, past_key_values, dec_hidden, dec_attn) + decoder_outputs = self.text_decoder( + input_ids=decoder_input_ids, + attention_mask=decoder_attention_mask, + encoder_hidden_states=encoder_outputs[0], + encoder_attention_mask=encoder_attention_mask, + past_key_values=past_key_values, + inputs_embeds=decoder_inputs_embeds, + use_cache=use_cache, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + + lm_logits = self.lm_head(decoder_outputs[0]) + + masked_lm_loss = None + if labels is not None: + loss_fct = CrossEntropyLoss() + labels = labels.to(lm_logits.device) + masked_lm_loss = loss_fct(lm_logits.view(-1, self.config.vocab_size), labels.view(-1)) + + if not return_dict: + outputs = decoder_outputs + encoder_outputs + output = (lm_logits,) + outputs[1:] + return ((masked_lm_loss,) + output) if masked_lm_loss is not None else output + + return Seq2SeqLMOutput( + loss=masked_lm_loss, + logits=lm_logits, + past_key_values=decoder_outputs.past_key_values, + decoder_hidden_states=decoder_outputs.hidden_states, + decoder_attentions=decoder_outputs.attentions, + cross_attentions=decoder_outputs.cross_attentions, + encoder_last_hidden_state=encoder_outputs.last_hidden_state, + encoder_hidden_states=encoder_outputs.hidden_states, + encoder_attentions=encoder_outputs.attentions, + ) + + @torch.no_grad() + def generate( + self, + input_features: torch.Tensor | None = None, + return_intermediate_token_ids: bool | None = None, + tgt_lang: str | None = None, + speaker_id: int | None = 0, + **kwargs, + ) -> torch.Tensor | SeamlessM4Tv2GenerationOutput: + """ + Generates translated audio waveforms. + + + + This method successively calls the `.generate` function of two different sub-models. You can specify keyword + arguments at two different levels: general arguments that will be passed to both models, or prefixed arguments + that will be passed to one of them. + + For example, calling `.generate(input_features, num_beams=4, speech_do_sample=True)` will successively perform + beam-search decoding on the text model, and multinomial beam-search sampling on the speech model. + + For an overview of generation strategies and code examples, check out the [following + guide](./generation_strategies). + + + + Args: + input_features (`torch.FloatTensor` of shape `(batch_size, sequence_length, num_banks)`): + Input audio features. This should be returned by the [`SeamlessM4TFeatureExtractor`] class or the + [`SeamlessM4TProcessor`] class. See [`SeamlessM4TFeatureExtractor.__call__`] for details. + return_intermediate_token_ids (`bool`, *optional*): + If `True`, also returns the intermediate generated text and unit tokens. Set to `True` if you also want + to get translated text alongside the audio. + tgt_lang (`str`, *optional*): + The language to use as target language for translation. + speaker_id (`int`, *optional*, defaults to 0): + The id of the speaker used for speech synthesis. Must be lower than `config.vocoder_num_spkrs`. + + kwargs (*optional*): + Remaining dictionary of keyword arguments that will be passed to [`GenerationMixin.generate`]. Keyword + arguments are of two types: + + - Without a prefix, they will be entered as `**kwargs` for the `generate` method of each sub-model, + except for `decoder_input_ids` which will only be passed through the text components. + - With a *text_* or *speech_* prefix, they will be input for the `generate` method of the + text model and speech model respectively. It has the priority over the keywords without a prefix. + + This means you can, for example, specify a generation strategy for one generation but not for the + other. + + + Returns: + `Union[SeamlessM4Tv2GenerationOutput, tuple[Tensor]]`: + - If `return_intermediate_token_ids`, returns [`SeamlessM4Tv2GenerationOutput`]. + - If not `return_intermediate_token_ids`, returns a tuple composed of waveforms of shape `(batch_size, + sequence_length)` and `waveform_lengths` which gives the length of each sample. + """ + batch_size = len(input_features) if input_features is not None else len(kwargs.get("inputs_embeds")) + + if tgt_lang is None: + raise ValueError("You must specify a `tgt_lang` to generate translated speech.") + else: + # also accept __xxx__ + tgt_lang = tgt_lang.replace("__", "") + for key in ["text_decoder_lang_to_code_id", "t2u_lang_code_to_id", "vocoder_lang_code_to_id"]: + lang_code_to_id = getattr(self.generation_config, key, None) + if lang_code_to_id is None: + raise ValueError( + f"""This model generation config doesn't have a `{key}` key which maps the target language + to the right token id. Make sure to load the right generation config.""" + ) + elif tgt_lang not in lang_code_to_id: + raise ValueError( + f"""`tgt_lang={tgt_lang}` is not supported by this model. + Please specify a `tgt_lang` in {",".join(lang_code_to_id.keys())}. Note that SeamlessM4Tv2 supports + more languages for text translation than for speech synthesis.""" + ) + + kwargs_text, kwargs_speech = format_speech_generation_kwargs(kwargs) + kwargs_text["output_hidden_states"] = True + kwargs_text["return_dict_in_generate"] = True + kwargs_text["output_scores"] = True + + text_decoder_input_ids = kwargs_text.get("decoder_input_ids") + # overwrite text_decoder_input_ids if tgt_lang is passed. The latter gets priority over decoder_input_ids. + text_tgt_lang_id = self.generation_config.text_decoder_lang_to_code_id.get(tgt_lang) + text_decoder_input_ids = torch.tensor([[text_tgt_lang_id]] * batch_size, device=self.device) + + kwargs_text["decoder_input_ids"] = text_decoder_input_ids + + # first generation + text_generation_output = super().generate(input_features, **kwargs_text) + sequences = text_generation_output.sequences + + # prepare second generation + num_return_sequences = len(sequences) // batch_size + attention_mask = kwargs_speech.get("attention_mask", kwargs_text.get("attention_mask", None)) + + # get last_hidden_state from encoder + encoder_hidden_states = self.speech_encoder(input_features=input_features, attention_mask=attention_mask)[0] + + # input modality = speech so new attention mask for the decoder + if attention_mask is not None: + sub_sampled_lengths = self._compute_sub_sample_lengths_from_attention_mask(attention_mask).to( + encoder_hidden_states.device + ) + attention_mask = _compute_new_attention_mask( + hidden_states=encoder_hidden_states, seq_lens=sub_sampled_lengths + ) + + # repeat attention mask alongside batch dimension + attention_mask = torch.repeat_interleave(attention_mask, num_return_sequences, dim=0) + + # repeat attention mask alongside batch dimension + encoder_hidden_states = torch.repeat_interleave(encoder_hidden_states, num_return_sequences, dim=0) + + # get decoder last hidden state - must do a pass through the text decoder + t2u_input_embeds = self.text_decoder( + input_ids=sequences[:, :-1], # Manually trim the final EOS token + encoder_hidden_states=encoder_hidden_states, + encoder_attention_mask=attention_mask, + ).last_hidden_state + + pad_token_id = self.generation_config.pad_token_id + + # Compute new attention mask + seq_lens = (sequences[:, :-1] != pad_token_id).int().sum(1) + t2u_model_attention_mask = _compute_new_attention_mask(t2u_input_embeds, seq_lens) + kwargs_speech["attention_mask"] = t2u_model_attention_mask + + # REMOVE EOS and lang_id + t2u_input_ids = sequences[:, 2:-1] + # replace every other EOS + t2u_input_ids = torch.masked_fill( + t2u_input_ids, t2u_input_ids == self.generation_config.eos_token_id, pad_token_id + ) + + # compute t2u_char_input_ids + t2u_subwords = self._indices_to_subwords(t2u_input_ids) + t2u_char_count_per_id = self._count_character_length_in_subword( + t2u_input_ids, t2u_subwords, pad_token_id=pad_token_id + ) + + # Add pads for lang, EOS tokens as per NLLB "source" tokenizer mode. + pad_zero = t2u_char_count_per_id.new_zeros((t2u_char_count_per_id.shape[0], 1)) + t2u_char_count_per_id = torch.cat([pad_zero, t2u_char_count_per_id, pad_zero], dim=1) + t2u_char_input_ids = self._get_char_input_ids( + t2u_input_ids, t2u_subwords, t2u_char_count_per_id, pad_token_id=pad_token_id + ) + + # second pass + t2u_output = self.t2u_model( + inputs_embeds=t2u_input_embeds, + char_input_ids=t2u_char_input_ids, + char_count_per_id=t2u_char_count_per_id, + **kwargs_speech, + ) + + t2u_logits = t2u_output[0] + padding_mask = t2u_output[1].bool() + + # The text-to-unit model is non auto-regressive. We keep the ability to use sampling with temperature + temperature = kwargs_speech.get("temperature", None) + if (temperature is None or temperature == 1.0) or not kwargs_speech.get("do_sample", False): + unit_ids = t2u_logits.argmax(dim=-1) + else: + t2u_logits = t2u_logits / temperature + # apply softmax + probs = nn.functional.softmax(t2u_logits, dim=-1) + # reshape to 2D: (batch_size, seq_len, t2u_vocab_size) -> (batch_size*seq_len, t2u_vocab_size) + probs = probs.reshape((-1, probs.shape[2])) + # multinomial then reshape : (batch_size*seq_len)-> (batch_size,seq_len) + unit_ids = torch.multinomial(probs, num_samples=1).view(t2u_logits.shape[0], -1) + + output_unit_ids = unit_ids.detach().clone() + + replace_mask = (unit_ids == self.config.t2u_eos_token_id) | (~padding_mask) + # replace eos per pad + unit_ids = unit_ids.masked_fill(replace_mask, self.config.t2u_pad_token_id) + + # offset of control symbols + unit_ids = torch.where( + unit_ids == self.config.t2u_pad_token_id, unit_ids, unit_ids - self.config.vocoder_offset + ) + + vocoder_tgt_lang_id = self.generation_config.vocoder_lang_code_to_id.get(tgt_lang) + vocoder_tgt_lang_id = torch.tensor([[vocoder_tgt_lang_id]] * len(unit_ids), device=self.device) + + speaker_id = torch.tensor([[speaker_id]] * len(unit_ids), device=self.device) + + waveform, waveform_lengths = self.vocoder( + input_ids=unit_ids, speaker_id=speaker_id, lang_id=vocoder_tgt_lang_id + ) + + if return_intermediate_token_ids: + return SeamlessM4Tv2GenerationOutput( + waveform=waveform, + waveform_lengths=waveform_lengths, + sequences=sequences, + unit_sequences=output_unit_ids, + ) + + return waveform, waveform_lengths + + +@auto_docstring( + custom_intro=""" + The original SeamlessM4Tv2 Model transformer which can be used for every tasks available (S2ST, S2TT, T2TT, T2ST). + """ +) +class SeamlessM4Tv2Model(SeamlessM4Tv2PreTrainedModel, GenerationMixin): + input_modalities = ("audio", "text") + output_modalities = ("audio", "text") + _tied_weights_keys = { + "lm_head.weight": "shared.weight", + "text_encoder.embed_tokens.weight": "shared.weight", + "text_decoder.embed_tokens.weight": "shared.weight", + } + + # Copied from transformers.models.seamless_m4t.modeling_seamless_m4t.SeamlessM4TModel.__init__ with SeamlessM4T->SeamlessM4Tv2 + def __init__(self, config, current_modality="text"): + r""" + current_modality (`str`, *optional*, defaults to `"text"`): + Default modality. Used to initialize the model. + """ + super().__init__(config) + + self.shared = nn.Embedding(config.vocab_size, config.hidden_size, config.pad_token_id) + + self.text_encoder = SeamlessM4Tv2Encoder(config) + self.speech_encoder = SeamlessM4Tv2SpeechEncoder(config) + self.text_decoder = SeamlessM4Tv2Decoder(config) + self.lm_head = nn.Linear(config.hidden_size, config.vocab_size, bias=False) + + self.current_modality = current_modality + if current_modality == "speech": + self.main_input_name = "input_features" + + # these models already call post_init in their initialization + self.t2u_model = SeamlessM4Tv2TextToUnitForConditionalGeneration(config) + self.vocoder = SeamlessM4Tv2CodeHifiGan(config) + + # Initialize weights and apply final processing + self.post_init() + + # Copied from transformers.models.seamless_m4t.modeling_seamless_m4t.SeamlessM4TModel.set_modality + def set_modality(self, modality="text"): + if modality == "text": + self.main_input_name = "input_ids" + self.current_modality = "text" + elif modality == "speech": + self.main_input_name = "input_features" + self.current_modality = "speech" + else: + raise ValueError(f"`modality={modality}` is not a valid modality. It must be `text` or `speech`.") + + # Copied from transformers.models.seamless_m4t.modeling_seamless_m4t.SeamlessM4TModel.get_encoder + def get_encoder(self): + if self.current_modality == "text": + return self.text_encoder + else: + return self.speech_encoder + + # Copied from transformers.models.seamless_m4t.modeling_seamless_m4t.SeamlessM4TModel.get_input_embeddings + def get_input_embeddings(self): + return self.text_decoder.embed_tokens + + # Copied from transformers.models.seamless_m4t.modeling_seamless_m4t.SeamlessM4TModel.set_input_embeddings + def set_input_embeddings(self, value): + self.text_encoder.embed_tokens = value + self.text_decoder.embed_tokens = value + self.shared = value + + @auto_docstring(custom_args=SEAMLESS_M4T_V2_COMMON_CUSTOM_ARGS) + # Copied from transformers.models.seamless_m4t.modeling_seamless_m4t.SeamlessM4TModel.forward with SeamlessM4T->SeamlessM4Tv2 + def forward( + self, + input_ids: torch.LongTensor | None = None, + input_features: torch.FloatTensor | None = None, + attention_mask: torch.Tensor | None = None, + decoder_input_ids: torch.LongTensor | None = None, + decoder_attention_mask: torch.LongTensor | None = None, + encoder_outputs: tuple[tuple[torch.FloatTensor]] | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.FloatTensor | None = None, + decoder_inputs_embeds: torch.FloatTensor | None = None, + labels: torch.LongTensor | None = None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + **kwargs, + ) -> Seq2SeqLMOutput | tuple[torch.FloatTensor]: + r""" + labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Labels for computing the masked language modeling loss. Indices should be in `[-100, 0, ..., + config.vocab_size]` (see `input_ids` docstring) Tokens with indices set to `-100` are ignored (masked), the + loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]` + """ + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + use_cache = use_cache if use_cache is not None else self.config.use_cache + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + if labels is not None: + if use_cache: + logger.warning("The `use_cache` argument is changed to `False` since `labels` is provided.") + use_cache = False + if decoder_input_ids is None and decoder_inputs_embeds is None: + decoder_input_ids = shift_tokens_right( + labels, self.config.pad_token_id, self.config.decoder_start_token_id + ) + + if input_ids is None and input_features is None and inputs_embeds is None and encoder_outputs is None: + raise ValueError( + "`input_ids`,`input_features`, `inputs_embeds` and `encoder_outputs` are all empty. Make sure at least one of them is not." + ) + elif input_features is not None: + if input_ids is not None: + logger.warning( + "`input_ids` is not `None` but `input_features` has been given." + "`input_features` will be used in priority through the `speech_encoder`. " + "Make sure that `input_features` and `input_ids` are mutually exclusive." + ) + + if inputs_embeds is not None: + logger.warning( + "`inputs_embeds` is not `None` but `input_features` has been given." + "`input_features` will be used in priority through `speech_encoder`. " + "`inputs_embeds` will be ignored." + ) + + # if encoder_outputs is not None, it's probably used within a .generate method so no need to warn + logger.warning( + "This calls the same method `forward` as `SeamlessM4Tv2ForTextToText` and `SeamlessM4Tv2ForSpeechToText`" + "depending on the input modality. If you want to generate speech, use the `generate` method." + ) + + self.set_modality("speech") + + encoder_outputs = self.speech_encoder( + input_features=input_features, + attention_mask=attention_mask, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + + elif input_ids is not None or inputs_embeds is not None: + # if encoder_outputs is not None, it's probably used within a .generate method so no need to warn + logger.warning( + "This calls the same method `forward` as `SeamlessM4Tv2ForTextToText` and `SeamlessM4Tv2ForSpeechToText`" + "depending on the input modality. If you want to generate speech, use the `generate` method." + ) + self.set_modality("text") + encoder_outputs = self.text_encoder( + input_ids=input_ids, + attention_mask=attention_mask, + inputs_embeds=inputs_embeds, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + # If the user passed a tuple for encoder_outputs, we wrap it in a BaseModelOutput when return_dict=True + elif return_dict and not isinstance(encoder_outputs, BaseModelOutput): + encoder_outputs = BaseModelOutput( + last_hidden_state=encoder_outputs[0], + hidden_states=encoder_outputs[1] if len(encoder_outputs) > 1 else None, + attentions=encoder_outputs[2] if len(encoder_outputs) > 2 else None, + ) + + encoder_attention_mask = attention_mask + # input modality = speech so new attention mask + if self.current_modality == "speech" and attention_mask is not None: + sub_sampled_lengths = self._compute_sub_sample_lengths_from_attention_mask(attention_mask).to( + encoder_outputs[0].device + ) + encoder_attention_mask = _compute_new_attention_mask( + hidden_states=encoder_outputs[0], seq_lens=sub_sampled_lengths + ) + + # decoder outputs consists of (dec_features, past_key_values, dec_hidden, dec_attn) + decoder_outputs = self.text_decoder( + input_ids=decoder_input_ids, + attention_mask=decoder_attention_mask, + encoder_hidden_states=encoder_outputs[0], + encoder_attention_mask=encoder_attention_mask, + past_key_values=past_key_values, + inputs_embeds=decoder_inputs_embeds, + use_cache=use_cache, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + + lm_logits = self.lm_head(decoder_outputs[0]) + + masked_lm_loss = None + if labels is not None: + loss_fct = CrossEntropyLoss() + labels = labels.to(lm_logits.device) + masked_lm_loss = loss_fct(lm_logits.view(-1, self.config.vocab_size), labels.view(-1)) + + if not return_dict: + outputs = decoder_outputs + encoder_outputs + output = (lm_logits,) + outputs[1:] + return ((masked_lm_loss,) + output) if masked_lm_loss is not None else output + + return Seq2SeqLMOutput( + loss=masked_lm_loss, + logits=lm_logits, + past_key_values=decoder_outputs.past_key_values, + decoder_hidden_states=decoder_outputs.hidden_states, + decoder_attentions=decoder_outputs.attentions, + cross_attentions=decoder_outputs.cross_attentions, + encoder_last_hidden_state=encoder_outputs.last_hidden_state, + encoder_hidden_states=encoder_outputs.hidden_states, + encoder_attentions=encoder_outputs.attentions, + ) + + @torch.no_grad() + def generate( + self, + input_ids: torch.Tensor | None = None, + input_features: torch.Tensor | None = None, + return_intermediate_token_ids: bool | None = None, + tgt_lang: str | None = None, + speaker_id: int | None = 0, + generate_speech: bool | None = True, + **kwargs, + ) -> torch.Tensor | SeamlessM4Tv2GenerationOutput: + """ + Generates translated token ids and/or translated audio waveforms. + + + + This method successively calls the `.generate` function of two different sub-models. You can specify keyword + arguments at two different levels: general arguments that will be passed to both models, or prefixed arguments + that will be passed to one of them. + + For example, calling `.generate(input_ids=input_ids, num_beams=4, speech_do_sample=True)` will successively + perform beam-search decoding on the text model, and multinomial beam-search sampling on the speech model. + + For an overview of generation strategies and code examples, check out the [following + guide](./generation_strategies). + + + + + Args: + input_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Indices of input sequence tokens in the vocabulary. + + Indices can be obtained using [`SeamlessM4TTokenizer`] or [`SeamlessM4TProcessor`]. See + [`PreTrainedTokenizer.encode`] and [`PreTrainedTokenizer.__call__`] for details. + + [What are input IDs?](../glossary#input-ids) + input_features (`torch.FloatTensor` of shape `(batch_size, sequence_length, num_banks)`, *optional*): + Input audio features. This should be returned by the [`SeamlessM4TFeatureExtractor`] class or the + [`SeamlessM4TProcessor`] class. See [`SeamlessM4TFeatureExtractor.__call__`] for details. + return_intermediate_token_ids (`bool`, *optional*): + If `True`, also returns the intermediate generated text and unit tokens. Set to `True` if you also want + to get translated text alongside the audio. + Note that if `generate_speech=False`, this parameter will be ignored and + the text tokens are returned. + tgt_lang (`str`, *optional*): + The language to use as target language for translation. + speaker_id (`int`, *optional*, defaults to 0): + The id of the speaker used for speech synthesis. Must be lower than `config.vocoder_num_spkrs`. + generate_speech (`bool`, *optional*, defaults to `True`): + If `False`, will only returns the text tokens and won't generate speech. + + kwargs (*optional*): + Remaining dictioy of keyword arguments that will be passed to [`GenerationMixin.generate`]. Keyword + arguments are of two types: + + - Without a prefix, they will be entered as `**kwargs` for the `generate` method of each sub-model, + except for `decoder_input_ids` which will only be passed through the text components. + - With a *text_* or *speech_* prefix, they will be input for the `generate` method of the + text model and speech model respectively. It has the priority over the keywords without a prefix. + + This means you can, for example, specify a generation strategy for one generation but not for the + other. + + Returns: + `Union[SeamlessM4Tv2GenerationOutput, tuple[Tensor], ModelOutput]`: + - If `generate_speech` and `return_intermediate_token_ids`, returns [`SeamlessM4Tv2GenerationOutput`]. + - If `generate_speech` and not `return_intermediate_token_ids`, returns a tuple composed of waveforms of + shape `(batch_size, sequence_length)` and `waveform_lengths` which gives the length of each sample. + - If `generate_speech=False`, it will returns `ModelOutput`. + """ + if input_ids is None and input_features is None and kwargs.get("inputs_embeds") is None: + raise ValueError( + "`input_ids`,`input_features` and `inputs_embeds` are all empty. Make sure at least one of them is not." + ) + + if generate_speech and tgt_lang is None: + raise ValueError("You must specify a `tgt_lang` to generate translated speech.") + + if tgt_lang is not None: + # also accept __xxx__ + tgt_lang = tgt_lang.replace("__", "") + if generate_speech: + keys_to_check = ["text_decoder_lang_to_code_id", "t2u_lang_code_to_id", "vocoder_lang_code_to_id"] + else: + keys_to_check = ["text_decoder_lang_to_code_id"] + for key in keys_to_check: + lang_code_to_id = getattr(self.generation_config, key, None) + if lang_code_to_id is None: + raise ValueError( + f"""This model generation config doesn't have a `{key}` key which maps the target language + to the right token id. Make sure to load the right generation config.""" + ) + elif tgt_lang not in lang_code_to_id: + raise ValueError( + f"""`tgt_lang={tgt_lang}` is not supported by this model. + Please specify a `tgt_lang` in {",".join(lang_code_to_id.keys())}. Note that SeamlessM4Tv2 supports + more languages for text translation than for speech synthesis.""" + ) + + batch_size = ( + len(input_features) + if input_features is not None + else (len(input_ids) if input_ids is not None else len(kwargs.get("inputs_embeds"))) + ) + + kwargs_text, kwargs_speech = format_speech_generation_kwargs(kwargs) + kwargs_text["output_hidden_states"] = True + kwargs_text["return_dict_in_generate"] = True + kwargs_text["output_scores"] = True + + text_decoder_input_ids = kwargs_text.get("decoder_input_ids") + # overwrite text_decoder_input_ids if tgt_lang is passed. The latter gets priority over decoder_input_ids. + if tgt_lang is not None: + # tgt_lang gets priority over decoder input ids + text_tgt_lang_id = self.generation_config.text_decoder_lang_to_code_id.get(tgt_lang) + text_decoder_input_ids = torch.tensor([[text_tgt_lang_id]] * batch_size, device=self.device) + + kwargs_text["decoder_input_ids"] = text_decoder_input_ids + + # first generation + if input_features is not None: + self.set_modality("speech") + if input_ids is not None: + logger.warning( + "`input_features` and `input_ids` are both non empty. `input_features` will be used in priority " + "through the speech encoder. Make sure `input_features=None` if you want to use the text encoder." + ) + text_generation_output = super().generate(input_features=input_features, **kwargs_text) + else: + self.set_modality("text") + text_generation_output = super().generate(input_ids=input_ids, input_features=None, **kwargs_text) + sequences = text_generation_output.sequences + + if not generate_speech: + return text_generation_output + + # prepare second generation + num_return_sequences = len(sequences) // batch_size + attention_mask = kwargs_speech.get("attention_mask", kwargs_text.get("attention_mask", None)) + + # get encoder last hidden states + if self.current_modality == "speech": + # get last_hidden_state from encoder - must do a pass through the speech encoder + encoder_hidden_states = self.speech_encoder( + input_features=input_features, attention_mask=attention_mask + ).last_hidden_state + + # input modality = speech so new attention mask for the decoder + if attention_mask is not None: + sub_sampled_lengths = self._compute_sub_sample_lengths_from_attention_mask(attention_mask).to( + encoder_hidden_states.device + ) + attention_mask = _compute_new_attention_mask( + hidden_states=encoder_hidden_states, seq_lens=sub_sampled_lengths + ) + else: + encoder_hidden_states = text_generation_output.encoder_hidden_states[-1] + + if attention_mask is not None: + # repeat attention mask alongside batch dimension + attention_mask = torch.repeat_interleave(attention_mask, num_return_sequences, dim=0) + + # repeat attention mask alongside batch dimension + encoder_hidden_states = torch.repeat_interleave(encoder_hidden_states, num_return_sequences, dim=0) + + # get decoder last hidden state - must do a pass through the text decoder + t2u_input_embeds = self.text_decoder( + input_ids=sequences[:, :-1], # Manually trim the final EOS token + encoder_hidden_states=encoder_hidden_states, + encoder_attention_mask=attention_mask, + ).last_hidden_state + + pad_token_id = self.generation_config.pad_token_id + + # Compute new attention mask + seq_lens = (sequences[:, :-1] != pad_token_id).int().sum(1) + t2u_model_attention_mask = _compute_new_attention_mask(t2u_input_embeds, seq_lens) + kwargs_speech["attention_mask"] = t2u_model_attention_mask + + # REMOVE EOS and lang_id + t2u_input_ids = sequences[:, 2:-1] + # replace every other EOS + t2u_input_ids = torch.masked_fill( + t2u_input_ids, t2u_input_ids == self.generation_config.eos_token_id, pad_token_id + ) + + # compute t2u_char_input_ids + t2u_subwords = self._indices_to_subwords(t2u_input_ids) + t2u_char_count_per_id = self._count_character_length_in_subword( + t2u_input_ids, t2u_subwords, pad_token_id=pad_token_id + ) + + # Add pads for lang, EOS tokens as per NLLB "source" tokenizer mode. + pad_zero = t2u_char_count_per_id.new_zeros((t2u_char_count_per_id.shape[0], 1)) + t2u_char_count_per_id = torch.cat([pad_zero, t2u_char_count_per_id, pad_zero], dim=1) + t2u_char_input_ids = self._get_char_input_ids( + t2u_input_ids, t2u_subwords, t2u_char_count_per_id, pad_token_id=pad_token_id + ) + + # second pass + t2u_output = self.t2u_model( + inputs_embeds=t2u_input_embeds, + char_input_ids=t2u_char_input_ids, + char_count_per_id=t2u_char_count_per_id, + **kwargs_speech, + ) + + t2u_logits = t2u_output[0] + padding_mask = t2u_output[1].bool() + + # The text-to-unit model is non auto-regressive. We keep the ability to use sampling with temperature + temperature = kwargs_speech.get("temperature", None) + if (temperature is None or temperature == 1.0) or not kwargs_speech.get("do_sample", False): + unit_ids = t2u_logits.argmax(dim=-1) + else: + t2u_logits = t2u_logits / temperature + # apply softmax + probs = nn.functional.softmax(t2u_logits, dim=-1) + # reshape to 2D: (batch_size, seq_len, t2u_vocab_size) -> (batch_size*seq_len, t2u_vocab_size) + probs = probs.reshape((-1, probs.shape[2])) + # multinomial then reshape : (batch_size*seq_len)-> (batch_size,seq_len) + unit_ids = torch.multinomial(probs, num_samples=1).view(t2u_logits.shape[0], -1) + + output_unit_ids = unit_ids.detach().clone() + + replace_mask = (unit_ids == self.config.t2u_eos_token_id) | (~padding_mask) + # replace eos per pad + unit_ids = unit_ids.masked_fill(replace_mask, self.config.t2u_pad_token_id) + + # offset of control symbols + unit_ids = torch.where( + unit_ids == self.config.t2u_pad_token_id, unit_ids, unit_ids - self.config.vocoder_offset + ) + + vocoder_tgt_lang_id = self.generation_config.vocoder_lang_code_to_id.get(tgt_lang) + vocoder_tgt_lang_id = torch.tensor([[vocoder_tgt_lang_id]] * len(unit_ids), device=self.device) + + speaker_id = torch.tensor([[speaker_id]] * len(unit_ids), device=self.device) + + waveform, waveform_lengths = self.vocoder( + input_ids=unit_ids, speaker_id=speaker_id, lang_id=vocoder_tgt_lang_id + ) + + if return_intermediate_token_ids: + return SeamlessM4Tv2GenerationOutput( + waveform=waveform, + waveform_lengths=waveform_lengths, + sequences=sequences, + unit_sequences=output_unit_ids, + ) + + return waveform, waveform_lengths + + +__all__ = [ + "SeamlessM4Tv2ForTextToSpeech", + "SeamlessM4Tv2ForSpeechToSpeech", + "SeamlessM4Tv2ForTextToText", + "SeamlessM4Tv2ForSpeechToText", + "SeamlessM4Tv2Model", + "SeamlessM4Tv2PreTrainedModel", +] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/seed_oss/__init__.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/seed_oss/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..ef9d0cb0f2103b2f7eed560f6835b1fd5a55b8ed --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/seed_oss/__init__.py @@ -0,0 +1,27 @@ +# Copyright 2025 Bytedance-Seed Ltd and the HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from typing import TYPE_CHECKING + +from ...utils import _LazyModule +from ...utils.import_utils import define_import_structure + + +if TYPE_CHECKING: + from .configuration_seed_oss import * + from .modeling_seed_oss import * +else: + import sys + + _file = globals()["__file__"] + sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__) diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/seed_oss/configuration_seed_oss.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/seed_oss/configuration_seed_oss.py new file mode 100644 index 0000000000000000000000000000000000000000..d9ccfb888bb5f1b31f58bb506c07b4684d849541 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/seed_oss/configuration_seed_oss.py @@ -0,0 +1,180 @@ +# Copyright 2025 Bytedance-Seed Ltd and the HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""SeedOss model configuration""" + +from ...configuration_utils import PreTrainedConfig +from ...modeling_rope_utils import RopeParameters + + +class SeedOssConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`SeedOssModel`]. It is used to instantiate an SeedOss + model according to the specified arguments, defining the model architecture. Instantiating a configuration with the + defaults will yield a similar configuration to that of the SeedOss-36B. + e.g. [ByteDance-Seed/SeedOss-36B](https://huggingface.co/ByteDance-Seed/SeedOss-36B) + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + + Args: + vocab_size (`int`, *optional*, defaults to 155136): + Vocabulary size of the SeedOss model. Defines the number of different tokens that can be represented by the + `inputs_ids` passed when calling [`SeedOssModel`] + hidden_size (`int`, *optional*, defaults to 4096): + Dimension of the hidden representations. + intermediate_size (`int`, *optional*, defaults to 27648): + Dimension of the MLP representations. + num_hidden_layers (`int`, *optional*, defaults to 64): + Number of hidden layers in the Transformer decoder. + num_attention_heads (`int`, *optional*, defaults to 80): + Number of attention heads for each attention layer in the Transformer decoder. + num_key_value_heads (`int`, *optional*, defaults to 8): + This is the number of key_value heads that should be used to implement Grouped Query Attention. If + `num_key_value_heads=num_attention_heads`, the model will use Multi Head Attention (MHA), if + `num_key_value_heads=1` the model will use Multi Query Attention (MQA) otherwise GQA is used. When + converting a multi-head checkpoint to a GQA checkpoint, each group key and value head should be constructed + by meanpooling all the original heads within that group. For more details, check out [this + paper](https://huggingface.co/papers/2305.13245). If it is not specified, will default to `8`. + hidden_act (`str` or `function`, *optional*, defaults to `"silu"`): + The non-linear activation function (function or string) in the decoder. + max_position_embeddings (`int`, *optional*, defaults to 524288): + The maximum sequence length that this model might ever be used with. + initializer_range (`float`, *optional*, defaults to 0.02): + The standard deviation of the truncated_normal_initializer for initializing all weight matrices. + rms_norm_eps (`float`, *optional*, defaults to 1e-06): + The epsilon used by the rms normalization layers. + use_cache (`bool`, *optional*, defaults to `True`): + Whether or not the model should return the last key/values attentions (not used by all models). Only + relevant if `config.is_decoder=True`. + pad_token_id (`int`, *optional*, defaults to 1): + Padding token id. + bos_token_id (`int`, *optional*, defaults to 0): + Beginning of stream token id. + eos_token_id (`int`, *optional*, defaults to 2): + End of stream token id. + pretraining_tp (`int`, *optional*, defaults to 1): + Experimental feature. Tensor parallelism rank used during pretraining. Please refer to [this + document](https://huggingface.co/docs/transformers/main/perf_train_gpu_many#tensor-parallelism) to + understand more about it. This value is necessary to ensure exact reproducibility of the pretraining + results. Please refer to [this issue](https://github.com/pytorch/pytorch/issues/76232). + tie_word_embeddings (`bool`, *optional*, defaults to `False`): + Whether to tie weight embeddings + rope_parameters (`RopeParameters`, *optional*): + Dictionary containing the configuration parameters for the RoPE embeddings. The dictionary should contain + a value for `rope_theta` and optionally parameters used for scaling in case you want to use RoPE + with longer `max_position_embeddings`. + attention_bias (`bool`, *optional*, defaults to `True`): + Whether to use a bias in the query, key, value layers during self-attention. + attention_out_bias (`bool`, *optional*, defaults to `False`): + Whether to use a bias in the output projection layer during self-attention. + attention_dropout (`float`, *optional*, defaults to 0.1): + The dropout ratio for the attention probabilities. + residual_dropout (`float`, *optional*, defaults to 0.1): + Residual connection dropout value. + mlp_bias (`bool`, *optional*, defaults to `False`): + Whether to use a bias in up_proj, down_proj and gate_proj layers in the MLP layers. + head_dim (`int`, *optional*, defaults to 128): + The attention head dimension. + + ```python + >>> from transformers import SeedOssModel, SeedOssConfig + + >>> # Initializing a SeedOss-36b style configuration + >>> configuration = SeedOssConfig() + + >>> # Initializing a model from the SeedOss-36b style configuration + >>> model = SeedOssModel(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "seed_oss" + keys_to_ignore_at_inference = ["past_key_values"] + # Default tensor parallel plan for base model `SeedOssModel` + base_model_tp_plan = { + "layers.*.self_attn.q_proj": "colwise", + "layers.*.self_attn.k_proj": "colwise", + "layers.*.self_attn.v_proj": "colwise", + "layers.*.self_attn.o_proj": "rowwise", + "layers.*.mlp.gate_proj": "colwise", + "layers.*.mlp.up_proj": "colwise", + "layers.*.mlp.down_proj": "rowwise", + } + base_model_pp_plan = { + "embed_tokens": (["input_ids"], ["inputs_embeds"]), + "layers": (["hidden_states", "attention_mask"], ["hidden_states"]), + "norm": (["hidden_states"], ["hidden_states"]), + } + + def __init__( + self, + vocab_size: int | None = 155136, + hidden_size: int | None = 4096, + intermediate_size: int | None = 27648, + num_hidden_layers: int | None = 64, + num_attention_heads: int | None = 80, + num_key_value_heads: int | None = 8, + hidden_act: str | None = "silu", + max_position_embeddings: int | None = 524288, + initializer_range: float | None = 0.02, + rms_norm_eps: float | None = 1e-6, + use_cache: bool | None = True, + pad_token_id: int | None = 1, + bos_token_id: int | None = 0, + eos_token_id: int | None = 2, + pretraining_tp: int | None = 1, + tie_word_embeddings: bool | None = False, + rope_parameters: RopeParameters | dict[str, RopeParameters] | None = None, + attention_bias: bool | None = True, + attention_out_bias: bool | None = False, + attention_dropout: float | None = 0.1, + residual_dropout: float | None = 0.1, + mlp_bias: bool | None = False, + head_dim: int | None = 128, + **kwargs, + ): + self.vocab_size = vocab_size + self.max_position_embeddings = max_position_embeddings + self.hidden_size = hidden_size + self.intermediate_size = intermediate_size + self.num_hidden_layers = num_hidden_layers + self.num_attention_heads = num_attention_heads + # for backward compatibility + if num_key_value_heads is None: + num_key_value_heads = num_attention_heads + + self.num_key_value_heads = num_key_value_heads + self.hidden_act = hidden_act + self.initializer_range = initializer_range + self.rms_norm_eps = rms_norm_eps + self.pretraining_tp = pretraining_tp + self.use_cache = use_cache + self.attention_bias = attention_bias + self.attention_out_bias = attention_out_bias + self.attention_dropout = attention_dropout + self.residual_dropout = residual_dropout + self.mlp_bias = mlp_bias + self.head_dim = head_dim if head_dim is not None else self.hidden_size // self.num_attention_heads + self.rope_parameters = rope_parameters + + self.tie_word_embeddings = tie_word_embeddings + self.pad_token_id = pad_token_id + self.bos_token_id = bos_token_id + self.eos_token_id = eos_token_id + super().__init__(**kwargs) + + +__all__ = ["SeedOssConfig"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/seed_oss/modeling_seed_oss.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/seed_oss/modeling_seed_oss.py new file mode 100644 index 0000000000000000000000000000000000000000..1cccc13d221b3c4721954f3e45fe70460ac1a62a --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/seed_oss/modeling_seed_oss.py @@ -0,0 +1,541 @@ +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# This file was automatically generated from src/transformers/models/seed_oss/modular_seed_oss.py. +# Do NOT edit this file manually as any edits will be overwritten by the generation of +# the file from the modular. If any change should be done, please apply the change to the +# modular_seed_oss.py file directly. One of our CI enforces this. +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# Copyright 2025 Bytedance-Seed Ltd and the HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +from collections.abc import Callable +from typing import Optional + +import torch +import torch.nn as nn + +from ...activations import ACT2FN +from ...cache_utils import Cache, DynamicCache +from ...generation import GenerationMixin +from ...integrations import use_kernel_forward_from_hub, use_kernel_func_from_hub +from ...masking_utils import create_causal_mask +from ...modeling_layers import ( + GenericForQuestionAnswering, + GenericForSequenceClassification, + GenericForTokenClassification, + GradientCheckpointingLayer, +) +from ...modeling_outputs import BaseModelOutputWithPast, CausalLMOutputWithPast +from ...modeling_rope_utils import ROPE_INIT_FUNCTIONS, dynamic_rope_update +from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel +from ...processing_utils import Unpack +from ...utils import TransformersKwargs, auto_docstring, can_return_tuple +from ...utils.generic import maybe_autocast, merge_with_config_defaults +from ...utils.output_capturing import capture_outputs +from .configuration_seed_oss import SeedOssConfig + + +@use_kernel_forward_from_hub("RMSNorm") +class SeedOssRMSNorm(nn.Module): + def __init__(self, hidden_size, eps: float = 1e-6) -> None: + """ + SeedOssRMSNorm is equivalent to T5LayerNorm + """ + super().__init__() + self.weight = nn.Parameter(torch.ones(hidden_size)) + self.variance_epsilon = eps + + def forward(self, hidden_states: torch.Tensor) -> torch.Tensor: + input_dtype = hidden_states.dtype + hidden_states = hidden_states.to(torch.float32) + variance = hidden_states.pow(2).mean(-1, keepdim=True) + hidden_states = hidden_states * torch.rsqrt(variance + self.variance_epsilon) + return self.weight * hidden_states.to(input_dtype) + + def extra_repr(self): + return f"{tuple(self.weight.shape)}, eps={self.variance_epsilon}" + + +class SeedOssMLP(nn.Module): + def __init__(self, config): + super().__init__() + self.config = config + self.hidden_size = config.hidden_size + self.intermediate_size = config.intermediate_size + self.gate_proj = nn.Linear(self.hidden_size, self.intermediate_size, bias=config.mlp_bias) + self.up_proj = nn.Linear(self.hidden_size, self.intermediate_size, bias=config.mlp_bias) + self.down_proj = nn.Linear(self.intermediate_size, self.hidden_size, bias=config.mlp_bias) + self.act_fn = ACT2FN[config.hidden_act] + self.residual_dropout = config.residual_dropout + + def forward(self, x): + down_proj = self.down_proj(self.act_fn(self.gate_proj(x)) * self.up_proj(x)) + down_proj = nn.functional.dropout(down_proj, p=self.residual_dropout, training=self.training) + return down_proj + + +def rotate_half(x): + """Rotates half the hidden dims of the input.""" + x1 = x[..., : x.shape[-1] // 2] + x2 = x[..., x.shape[-1] // 2 :] + return torch.cat((-x2, x1), dim=-1) + + +@use_kernel_func_from_hub("rotary_pos_emb") +def apply_rotary_pos_emb(q, k, cos, sin, unsqueeze_dim=1): + """Applies Rotary Position Embedding to the query and key tensors. + + Args: + q (`torch.Tensor`): The query tensor. + k (`torch.Tensor`): The key tensor. + cos (`torch.Tensor`): The cosine part of the rotary embedding. + sin (`torch.Tensor`): The sine part of the rotary embedding. + unsqueeze_dim (`int`, *optional*, defaults to 1): + The 'unsqueeze_dim' argument specifies the dimension along which to unsqueeze cos[position_ids] and + sin[position_ids] so that they can be properly broadcasted to the dimensions of q and k. For example, note + that cos[position_ids] and sin[position_ids] have the shape [batch_size, seq_len, head_dim]. Then, if q and + k have the shape [batch_size, heads, seq_len, head_dim], then setting unsqueeze_dim=1 makes + cos[position_ids] and sin[position_ids] broadcastable to the shapes of q and k. Similarly, if q and k have + the shape [batch_size, seq_len, heads, head_dim], then set unsqueeze_dim=2. + Returns: + `tuple(torch.Tensor)` comprising of the query and key tensors rotated using the Rotary Position Embedding. + """ + cos = cos.unsqueeze(unsqueeze_dim) + sin = sin.unsqueeze(unsqueeze_dim) + q_embed = (q * cos) + (rotate_half(q) * sin) + k_embed = (k * cos) + (rotate_half(k) * sin) + return q_embed, k_embed + + +def repeat_kv(hidden_states: torch.Tensor, n_rep: int) -> torch.Tensor: + """ + This is the equivalent of torch.repeat_interleave(x, dim=1, repeats=n_rep). The hidden states go from (batch, + num_key_value_heads, seqlen, head_dim) to (batch, num_attention_heads, seqlen, head_dim) + """ + batch, num_key_value_heads, slen, head_dim = hidden_states.shape + if n_rep == 1: + return hidden_states + hidden_states = hidden_states[:, :, None, :, :].expand(batch, num_key_value_heads, n_rep, slen, head_dim) + return hidden_states.reshape(batch, num_key_value_heads * n_rep, slen, head_dim) + + +def eager_attention_forward( + module: nn.Module, + query: torch.Tensor, + key: torch.Tensor, + value: torch.Tensor, + attention_mask: torch.Tensor | None, + scaling: float, + dropout: float = 0.0, + **kwargs: Unpack[TransformersKwargs], +): + key_states = repeat_kv(key, module.num_key_value_groups) + value_states = repeat_kv(value, module.num_key_value_groups) + + attn_weights = torch.matmul(query, key_states.transpose(2, 3)) * scaling + if attention_mask is not None: + attn_weights = attn_weights + attention_mask + + attn_weights = nn.functional.softmax(attn_weights, dim=-1, dtype=torch.float32).to(query.dtype) + attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training) + attn_output = torch.matmul(attn_weights, value_states) + attn_output = attn_output.transpose(1, 2).contiguous() + + return attn_output, attn_weights + + +class SeedOssAttention(nn.Module): + def __init__(self, config: SeedOssConfig, layer_idx: int): + super().__init__() + self.config = config + self.layer_idx = layer_idx + self.head_dim = config.head_dim + self.num_key_value_heads = config.num_key_value_heads + self.num_attention_heads = config.num_attention_heads + self.num_key_value_groups = self.num_attention_heads // self.num_key_value_heads + self.scaling = self.head_dim**-0.5 + self.attention_dropout = config.attention_dropout + self.is_causal = True + + self.q_proj = nn.Linear( + config.hidden_size, self.num_attention_heads * self.head_dim, bias=config.attention_bias + ) + self.k_proj = nn.Linear( + config.hidden_size, config.num_key_value_heads * self.head_dim, bias=config.attention_bias + ) + self.v_proj = nn.Linear( + config.hidden_size, config.num_key_value_heads * self.head_dim, bias=config.attention_bias + ) + self.o_proj = nn.Linear( + self.num_attention_heads * self.head_dim, config.hidden_size, bias=config.attention_out_bias + ) + + self.residual_dropout = config.residual_dropout + + def forward( + self, + hidden_states: torch.Tensor, + position_embeddings: tuple[torch.Tensor, torch.Tensor], + attention_mask: torch.Tensor | None, + past_key_values: Cache | None = None, + cache_position: torch.LongTensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor, torch.Tensor]: + input_shape = hidden_states.shape[:-1] + hidden_shape = (*input_shape, -1, self.head_dim) + + query_states = self.q_proj(hidden_states).view(hidden_shape).transpose(1, 2) + key_states = self.k_proj(hidden_states).view(hidden_shape).transpose(1, 2) + value_states = self.v_proj(hidden_states).view(hidden_shape).transpose(1, 2) + + cos, sin = position_embeddings + query_states, key_states = apply_rotary_pos_emb(query_states, key_states, cos, sin) + + if past_key_values is not None: + # sin and cos are specific to RoPE models; cache_position needed for the static cache + cache_kwargs = {"sin": sin, "cos": cos, "cache_position": cache_position} + key_states, value_states = past_key_values.update(key_states, value_states, self.layer_idx, cache_kwargs) + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, eager_attention_forward + ) + + attn_output, attn_weights = attention_interface( + self, + query_states, + key_states, + value_states, + attention_mask, + dropout=0.0 if not self.training else self.attention_dropout, + scaling=self.scaling, + **kwargs, + ) + + attn_output = attn_output.reshape(*input_shape, -1).contiguous() + attn_output = self.o_proj(attn_output) + attn_output = nn.functional.dropout(attn_output, p=self.residual_dropout, training=self.training) + + return attn_output, attn_weights + + +class SeedOssDecoderLayer(GradientCheckpointingLayer): + def __init__(self, config: SeedOssConfig, layer_idx: int): + super().__init__() + self.hidden_size = config.hidden_size + + self.self_attn = SeedOssAttention(config=config, layer_idx=layer_idx) + + self.mlp = SeedOssMLP(config) + self.input_layernorm = SeedOssRMSNorm(config.hidden_size, eps=config.rms_norm_eps) + self.post_attention_layernorm = SeedOssRMSNorm(config.hidden_size, eps=config.rms_norm_eps) + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.Tensor | None = None, + position_ids: torch.LongTensor | None = None, + past_key_values: Cache | None = None, + use_cache: bool | None = False, + cache_position: torch.LongTensor | None = None, + position_embeddings: tuple[torch.Tensor, torch.Tensor] | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> torch.Tensor: + residual = hidden_states + hidden_states = self.input_layernorm(hidden_states) + # Self Attention + hidden_states, _ = self.self_attn( + hidden_states=hidden_states, + attention_mask=attention_mask, + position_ids=position_ids, + past_key_values=past_key_values, + use_cache=use_cache, + cache_position=cache_position, + position_embeddings=position_embeddings, + **kwargs, + ) + hidden_states = residual + hidden_states + + # Fully Connected + residual = hidden_states + hidden_states = self.post_attention_layernorm(hidden_states) + hidden_states = self.mlp(hidden_states) + hidden_states = residual + hidden_states + return hidden_states + + +@auto_docstring +class SeedOssPreTrainedModel(PreTrainedModel): + config: SeedOssConfig + base_model_prefix = "model" + supports_gradient_checkpointing = True + _no_split_modules = ["SeedOssDecoderLayer"] + _skip_keys_device_placement = ["past_key_values"] + _supports_flash_attn = True + _supports_sdpa = True + _supports_flex_attn = True + + _can_compile_fullgraph = True + _supports_attention_backend = True + _can_record_outputs = { + "hidden_states": SeedOssDecoderLayer, + "attentions": SeedOssAttention, + } + + +class SeedOssRotaryEmbedding(nn.Module): + inv_freq: torch.Tensor # fix linting for `register_buffer` + + def __init__(self, config: SeedOssConfig, device=None): + super().__init__() + self.max_seq_len_cached = config.max_position_embeddings + self.original_max_seq_len = config.max_position_embeddings + + self.config = config + + self.rope_type = self.config.rope_parameters["rope_type"] + rope_init_fn: Callable = self.compute_default_rope_parameters + if self.rope_type != "default": + rope_init_fn = ROPE_INIT_FUNCTIONS[self.rope_type] + inv_freq, self.attention_scaling = rope_init_fn(self.config, device) + + self.register_buffer("inv_freq", inv_freq, persistent=False) + self.register_buffer("original_inv_freq", inv_freq.clone(), persistent=False) + + @staticmethod + def compute_default_rope_parameters( + config: SeedOssConfig | None = None, + device: Optional["torch.device"] = None, + seq_len: int | None = None, + ) -> tuple["torch.Tensor", float]: + """ + Computes the inverse frequencies according to the original RoPE implementation + Args: + config ([`~transformers.PreTrainedConfig`]): + The model configuration. + device (`torch.device`): + The device to use for initialization of the inverse frequencies. + seq_len (`int`, *optional*): + The current sequence length. Unused for this type of RoPE. + Returns: + Tuple of (`torch.Tensor`, `float`), containing the inverse frequencies for the RoPE embeddings and the + post-processing scaling factor applied to the computed cos/sin (unused in this type of RoPE). + """ + base = config.rope_parameters["rope_theta"] + dim = getattr(config, "head_dim", None) or config.hidden_size // config.num_attention_heads + + attention_factor = 1.0 # Unused in this type of RoPE + + # Compute the inverse frequencies + inv_freq = 1.0 / ( + base ** (torch.arange(0, dim, 2, dtype=torch.int64).to(device=device, dtype=torch.float) / dim) + ) + return inv_freq, attention_factor + + @torch.no_grad() + @dynamic_rope_update # power user: used with advanced RoPE types (e.g. dynamic rope) + def forward(self, x, position_ids): + inv_freq_expanded = self.inv_freq[None, :, None].float().expand(position_ids.shape[0], -1, 1).to(x.device) + position_ids_expanded = position_ids[:, None, :].float() + + device_type = x.device.type if isinstance(x.device.type, str) and x.device.type != "mps" else "cpu" + with maybe_autocast(device_type=device_type, enabled=False): # Force float32 + freqs = (inv_freq_expanded.float() @ position_ids_expanded.float()).transpose(1, 2) + emb = torch.cat((freqs, freqs), dim=-1) + cos = emb.cos() * self.attention_scaling + sin = emb.sin() * self.attention_scaling + + return cos.to(dtype=x.dtype), sin.to(dtype=x.dtype) + + +@auto_docstring +class SeedOssModel(SeedOssPreTrainedModel): + def __init__(self, config: SeedOssConfig): + super().__init__(config) + self.padding_idx = config.pad_token_id + self.vocab_size = config.vocab_size + + self.embed_tokens = nn.Embedding(config.vocab_size, config.hidden_size, self.padding_idx) + self.layers = nn.ModuleList( + [SeedOssDecoderLayer(config, layer_idx) for layer_idx in range(config.num_hidden_layers)] + ) + self.norm = SeedOssRMSNorm(config.hidden_size, eps=config.rms_norm_eps) + self.rotary_emb = SeedOssRotaryEmbedding(config=config) + self.gradient_checkpointing = False + + # Initialize weights and apply final processing + self.post_init() + + @merge_with_config_defaults + @capture_outputs + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.Tensor | None = None, + position_ids: torch.LongTensor | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.FloatTensor | None = None, + cache_position: torch.LongTensor | None = None, + use_cache: bool | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> BaseModelOutputWithPast: + if (input_ids is None) ^ (inputs_embeds is not None): + raise ValueError("You must specify exactly one of input_ids or inputs_embeds") + + if inputs_embeds is None: + inputs_embeds: torch.Tensor = self.embed_tokens(input_ids) + + if use_cache and past_key_values is None: + past_key_values = DynamicCache(config=self.config) + + if cache_position is None: + past_seen_tokens = past_key_values.get_seq_length() if past_key_values is not None else 0 + cache_position: torch.Tensor = ( + torch.arange(inputs_embeds.shape[1], device=inputs_embeds.device) + past_seen_tokens + ) + + if position_ids is None: + position_ids = cache_position.unsqueeze(0) + + causal_mask = create_causal_mask( + config=self.config, + inputs_embeds=inputs_embeds, + attention_mask=attention_mask, + cache_position=cache_position, + past_key_values=past_key_values, + position_ids=position_ids, + ) + + hidden_states = inputs_embeds + position_embeddings = self.rotary_emb(hidden_states, position_ids=position_ids) + + for decoder_layer in self.layers[: self.config.num_hidden_layers]: + hidden_states = decoder_layer( + hidden_states, + attention_mask=causal_mask, + position_embeddings=position_embeddings, + position_ids=position_ids, + past_key_values=past_key_values, + use_cache=use_cache, + cache_position=cache_position, + **kwargs, + ) + + hidden_states = self.norm(hidden_states) + return BaseModelOutputWithPast( + last_hidden_state=hidden_states, + past_key_values=past_key_values, + ) + + +@auto_docstring +class SeedOssForCausalLM(SeedOssPreTrainedModel, GenerationMixin): + _tied_weights_keys = {"lm_head.weight": "model.embed_tokens.weight"} + _tp_plan = {"lm_head": "colwise_gather_output"} + _pp_plan = {"lm_head": (["hidden_states"], ["logits"])} + + def __init__(self, config): + super().__init__(config) + self.model = SeedOssModel(config) + self.vocab_size = config.vocab_size + self.lm_head = nn.Linear(config.hidden_size, config.vocab_size, bias=False) + + # Initialize weights and apply final processing + self.post_init() + + @can_return_tuple + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.Tensor | None = None, + position_ids: torch.LongTensor | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.FloatTensor | None = None, + labels: torch.LongTensor | None = None, + use_cache: bool | None = None, + cache_position: torch.LongTensor | None = None, + logits_to_keep: int | torch.Tensor = 0, + **kwargs: Unpack[TransformersKwargs], + ) -> CausalLMOutputWithPast: + r""" + labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Labels for computing the masked language modeling loss. Indices should either be in `[0, ..., + config.vocab_size]` or -100 (see `input_ids` docstring). Tokens with indices set to `-100` are ignored + (masked), the loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]`. + + Example: + + ```python + >>> from transformers import AutoTokenizer, SeedOssForCausalLM + + >>> model = SeedOssForCausalLM.from_pretrained("ByteDance-Seed/SeedOss-36B") + >>> tokenizer = AutoTokenizer.from_pretrained("ByteDance-Seed/SeedOss-36B") + + >>> prompt = "Hey, are you conscious? Can you talk to me?" + >>> inputs = tokenizer(prompt, return_tensors="pt") + + >>> # Generate + >>> generate_ids = model.generate(inputs.input_ids, max_length=30) + >>> tokenizer.batch_decode(generate_ids, skip_special_tokens=True, clean_up_tokenization_spaces=False)[0] + "Hey, are you conscious? Can you talk to me?\nI'm not conscious, but I can talk to you." + ```""" + outputs: BaseModelOutputWithPast = self.model( + input_ids=input_ids, + attention_mask=attention_mask, + position_ids=position_ids, + past_key_values=past_key_values, + inputs_embeds=inputs_embeds, + use_cache=use_cache, + cache_position=cache_position, + **kwargs, + ) + + hidden_states = outputs.last_hidden_state + # Only compute necessary logits, and do not upcast them to float if we are not computing the loss + slice_indices = slice(-logits_to_keep, None) if isinstance(logits_to_keep, int) else logits_to_keep + logits = self.lm_head(hidden_states[:, slice_indices, :]) + + loss = None + if labels is not None: + loss = self.loss_function(logits=logits, labels=labels, vocab_size=self.config.vocab_size, **kwargs) + + return CausalLMOutputWithPast( + loss=loss, + logits=logits, + past_key_values=outputs.past_key_values, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + ) + + +class SeedOssForSequenceClassification(GenericForSequenceClassification, SeedOssPreTrainedModel): + pass + + +class SeedOssForTokenClassification(GenericForTokenClassification, SeedOssPreTrainedModel): + pass + + +class SeedOssForQuestionAnswering(GenericForQuestionAnswering, SeedOssPreTrainedModel): + base_model_prefix = "transformer" # For BC, where `transformer` was used instead of `model` + + +__all__ = [ + "SeedOssForCausalLM", + "SeedOssForQuestionAnswering", + "SeedOssPreTrainedModel", + "SeedOssModel", + "SeedOssForSequenceClassification", + "SeedOssForTokenClassification", +] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/seed_oss/modular_seed_oss.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/seed_oss/modular_seed_oss.py new file mode 100644 index 0000000000000000000000000000000000000000..305e36549ee0a03cf24a207f77df68002a53cdc6 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/seed_oss/modular_seed_oss.py @@ -0,0 +1,204 @@ +# Copyright 2025 Bytedance-Seed Ltd and the HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""PyTorch SeedOss model.""" + +from collections.abc import Callable + +import torch +import torch.nn as nn + +from ...activations import ACT2FN +from ...cache_utils import Cache +from ...modeling_outputs import CausalLMOutputWithPast +from ...modeling_utils import ALL_ATTENTION_FUNCTIONS +from ...processing_utils import Unpack +from ...utils import TransformersKwargs, logging +from ..llama.modeling_llama import ( + LlamaDecoderLayer, + LlamaForCausalLM, + LlamaForQuestionAnswering, + LlamaForSequenceClassification, + LlamaForTokenClassification, + LlamaModel, + LlamaPreTrainedModel, + LlamaRMSNorm, + apply_rotary_pos_emb, + eager_attention_forward, +) +from .configuration_seed_oss import SeedOssConfig + + +logger = logging.get_logger(__name__) + +_CHECKPOINT_FOR_DOC = "ByteDance-Seed/SeedOss-36B" + + +class SeedOssRMSNorm(LlamaRMSNorm): + pass + + +class SeedOssMLP(nn.Module): + def __init__(self, config): + super().__init__() + self.config = config + self.hidden_size = config.hidden_size + self.intermediate_size = config.intermediate_size + self.gate_proj = nn.Linear(self.hidden_size, self.intermediate_size, bias=config.mlp_bias) + self.up_proj = nn.Linear(self.hidden_size, self.intermediate_size, bias=config.mlp_bias) + self.down_proj = nn.Linear(self.intermediate_size, self.hidden_size, bias=config.mlp_bias) + self.act_fn = ACT2FN[config.hidden_act] + self.residual_dropout = config.residual_dropout + + def forward(self, x): + down_proj = self.down_proj(self.act_fn(self.gate_proj(x)) * self.up_proj(x)) + down_proj = nn.functional.dropout(down_proj, p=self.residual_dropout, training=self.training) + return down_proj + + +class SeedOssAttention(nn.Module): + def __init__(self, config: SeedOssConfig, layer_idx: int): + super().__init__() + self.config = config + self.layer_idx = layer_idx + self.head_dim = config.head_dim + self.num_key_value_heads = config.num_key_value_heads + self.num_attention_heads = config.num_attention_heads + self.num_key_value_groups = self.num_attention_heads // self.num_key_value_heads + self.scaling = self.head_dim**-0.5 + self.attention_dropout = config.attention_dropout + self.is_causal = True + + self.q_proj = nn.Linear( + config.hidden_size, self.num_attention_heads * self.head_dim, bias=config.attention_bias + ) + self.k_proj = nn.Linear( + config.hidden_size, config.num_key_value_heads * self.head_dim, bias=config.attention_bias + ) + self.v_proj = nn.Linear( + config.hidden_size, config.num_key_value_heads * self.head_dim, bias=config.attention_bias + ) + self.o_proj = nn.Linear( + self.num_attention_heads * self.head_dim, config.hidden_size, bias=config.attention_out_bias + ) + + self.residual_dropout = config.residual_dropout + + def forward( + self, + hidden_states: torch.Tensor, + position_embeddings: tuple[torch.Tensor, torch.Tensor], + attention_mask: torch.Tensor | None, + past_key_values: Cache | None = None, + cache_position: torch.LongTensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple[torch.Tensor, torch.Tensor]: + input_shape = hidden_states.shape[:-1] + hidden_shape = (*input_shape, -1, self.head_dim) + + query_states = self.q_proj(hidden_states).view(hidden_shape).transpose(1, 2) + key_states = self.k_proj(hidden_states).view(hidden_shape).transpose(1, 2) + value_states = self.v_proj(hidden_states).view(hidden_shape).transpose(1, 2) + + cos, sin = position_embeddings + query_states, key_states = apply_rotary_pos_emb(query_states, key_states, cos, sin) + + if past_key_values is not None: + # sin and cos are specific to RoPE models; cache_position needed for the static cache + cache_kwargs = {"sin": sin, "cos": cos, "cache_position": cache_position} + key_states, value_states = past_key_values.update(key_states, value_states, self.layer_idx, cache_kwargs) + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, eager_attention_forward + ) + + attn_output, attn_weights = attention_interface( + self, + query_states, + key_states, + value_states, + attention_mask, + dropout=0.0 if not self.training else self.attention_dropout, + scaling=self.scaling, + **kwargs, + ) + + attn_output = attn_output.reshape(*input_shape, -1).contiguous() + attn_output = self.o_proj(attn_output) + attn_output = nn.functional.dropout(attn_output, p=self.residual_dropout, training=self.training) + + return attn_output, attn_weights + + +class SeedOssDecoderLayer(LlamaDecoderLayer): + pass + + +class SeedOssPreTrainedModel(LlamaPreTrainedModel): + pass + + +class SeedOssModel(LlamaModel): + pass + + +class SeedOssForCausalLM(LlamaForCausalLM): + def forward( + self, + **super_kwargs: Unpack[TransformersKwargs], + ) -> CausalLMOutputWithPast: + r""" + labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Labels for computing the masked language modeling loss. Indices should either be in `[0, ..., + config.vocab_size]` or -100 (see `input_ids` docstring). Tokens with indices set to `-100` are ignored + (masked), the loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]`. + + Example: + + ```python + >>> from transformers import AutoTokenizer, SeedOssForCausalLM + + >>> model = SeedOssForCausalLM.from_pretrained("ByteDance-Seed/SeedOss-36B") + >>> tokenizer = AutoTokenizer.from_pretrained("ByteDance-Seed/SeedOss-36B") + + >>> prompt = "Hey, are you conscious? Can you talk to me?" + >>> inputs = tokenizer(prompt, return_tensors="pt") + + >>> # Generate + >>> generate_ids = model.generate(inputs.input_ids, max_length=30) + >>> tokenizer.batch_decode(generate_ids, skip_special_tokens=True, clean_up_tokenization_spaces=False)[0] + "Hey, are you conscious? Can you talk to me?\nI'm not conscious, but I can talk to you." + ```""" + return super().forward(**super_kwargs) + + +class SeedOssForSequenceClassification(LlamaForSequenceClassification): + pass + + +class SeedOssForTokenClassification(LlamaForTokenClassification): + pass + + +class SeedOssForQuestionAnswering(LlamaForQuestionAnswering): + pass + + +__all__ = [ + "SeedOssForCausalLM", + "SeedOssForQuestionAnswering", + "SeedOssPreTrainedModel", + "SeedOssModel", + "SeedOssForSequenceClassification", + "SeedOssForTokenClassification", +] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/segformer/__init__.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/segformer/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..c9b88d1a98c664ce7aab5e8e7928dcd23ef42a50 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/segformer/__init__.py @@ -0,0 +1,30 @@ +# Copyright 2024 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from typing import TYPE_CHECKING + +from ...utils import _LazyModule +from ...utils.import_utils import define_import_structure + + +if TYPE_CHECKING: + from .configuration_segformer import * + from .feature_extraction_segformer import * + from .image_processing_segformer import * + from .image_processing_segformer_fast import * + from .modeling_segformer import * +else: + import sys + + _file = globals()["__file__"] + sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__) diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/segformer/configuration_segformer.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/segformer/configuration_segformer.py new file mode 100644 index 0000000000000000000000000000000000000000..6e57ff0dd85ecb6453524ada88e635f69b2e1e9d --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/segformer/configuration_segformer.py @@ -0,0 +1,136 @@ +# Copyright 2021 NVIDIA and The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""SegFormer model configuration""" + +from ...configuration_utils import PreTrainedConfig +from ...utils import logging + + +logger = logging.get_logger(__name__) + + +class SegformerConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`SegformerModel`]. It is used to instantiate an + SegFormer model according to the specified arguments, defining the model architecture. Instantiating a + configuration with the defaults will yield a similar configuration to that of the SegFormer + [nvidia/segformer-b0-finetuned-ade-512-512](https://huggingface.co/nvidia/segformer-b0-finetuned-ade-512-512) + architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + num_channels (`int`, *optional*, defaults to 3): + The number of input channels. + num_encoder_blocks (`int`, *optional*, defaults to 4): + The number of encoder blocks (i.e. stages in the Mix Transformer encoder). + depths (`list[int]`, *optional*, defaults to `[2, 2, 2, 2]`): + The number of layers in each encoder block. + sr_ratios (`list[int]`, *optional*, defaults to `[8, 4, 2, 1]`): + Sequence reduction ratios in each encoder block. + hidden_sizes (`list[int]`, *optional*, defaults to `[32, 64, 160, 256]`): + Dimension of each of the encoder blocks. + patch_sizes (`list[int]`, *optional*, defaults to `[7, 3, 3, 3]`): + Patch size before each encoder block. + strides (`list[int]`, *optional*, defaults to `[4, 2, 2, 2]`): + Stride before each encoder block. + num_attention_heads (`list[int]`, *optional*, defaults to `[1, 2, 5, 8]`): + Number of attention heads for each attention layer in each block of the Transformer encoder. + mlp_ratios (`list[int]`, *optional*, defaults to `[4, 4, 4, 4]`): + Ratio of the size of the hidden layer compared to the size of the input layer of the Mix FFNs in the + encoder blocks. + hidden_act (`str` or `function`, *optional*, defaults to `"gelu"`): + The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`, + `"relu"`, `"selu"` and `"gelu_new"` are supported. + hidden_dropout_prob (`float`, *optional*, defaults to 0.0): + The dropout probability for all fully connected layers in the embeddings, encoder, and pooler. + attention_probs_dropout_prob (`float`, *optional*, defaults to 0.0): + The dropout ratio for the attention probabilities. + classifier_dropout_prob (`float`, *optional*, defaults to 0.1): + The dropout probability before the classification head. + initializer_range (`float`, *optional*, defaults to 0.02): + The standard deviation of the truncated_normal_initializer for initializing all weight matrices. + drop_path_rate (`float`, *optional*, defaults to 0.1): + The dropout probability for stochastic depth, used in the blocks of the Transformer encoder. + layer_norm_eps (`float`, *optional*, defaults to 1e-06): + The epsilon used by the layer normalization layers. + decoder_hidden_size (`int`, *optional*, defaults to 256): + The dimension of the all-MLP decode head. + semantic_loss_ignore_index (`int`, *optional*, defaults to 255): + The index that is ignored by the loss function of the semantic segmentation model. + + Example: + + ```python + >>> from transformers import SegformerModel, SegformerConfig + + >>> # Initializing a SegFormer nvidia/segformer-b0-finetuned-ade-512-512 style configuration + >>> configuration = SegformerConfig() + + >>> # Initializing a model from the nvidia/segformer-b0-finetuned-ade-512-512 style configuration + >>> model = SegformerModel(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "segformer" + + def __init__( + self, + num_channels=3, + num_encoder_blocks=4, + depths=[2, 2, 2, 2], + sr_ratios=[8, 4, 2, 1], + hidden_sizes=[32, 64, 160, 256], + patch_sizes=[7, 3, 3, 3], + strides=[4, 2, 2, 2], + num_attention_heads=[1, 2, 5, 8], + mlp_ratios=[4, 4, 4, 4], + hidden_act="gelu", + hidden_dropout_prob=0.0, + attention_probs_dropout_prob=0.0, + classifier_dropout_prob=0.1, + initializer_range=0.02, + drop_path_rate=0.1, + layer_norm_eps=1e-6, + decoder_hidden_size=256, + semantic_loss_ignore_index=255, + **kwargs, + ): + super().__init__(**kwargs) + + self.num_channels = num_channels + self.num_encoder_blocks = num_encoder_blocks + self.depths = depths + self.sr_ratios = sr_ratios + self.hidden_sizes = hidden_sizes + self.patch_sizes = patch_sizes + self.strides = strides + self.mlp_ratios = mlp_ratios + self.num_attention_heads = num_attention_heads + self.hidden_act = hidden_act + self.hidden_dropout_prob = hidden_dropout_prob + self.attention_probs_dropout_prob = attention_probs_dropout_prob + self.classifier_dropout_prob = classifier_dropout_prob + self.initializer_range = initializer_range + self.drop_path_rate = drop_path_rate + self.layer_norm_eps = layer_norm_eps + self.decoder_hidden_size = decoder_hidden_size + self.reshape_last_stage = kwargs.get("reshape_last_stage", True) + self.semantic_loss_ignore_index = semantic_loss_ignore_index + + +__all__ = ["SegformerConfig"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/segformer/image_processing_segformer.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/segformer/image_processing_segformer.py new file mode 100644 index 0000000000000000000000000000000000000000..b0e04b3e4d1fda6bedba97c51450aeee5204d28d --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/segformer/image_processing_segformer.py @@ -0,0 +1,475 @@ +# Copyright 2022 The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""Image processor class for Segformer.""" + +import numpy as np + +from ...image_processing_utils import INIT_SERVICE_KWARGS, BaseImageProcessor, BatchFeature, get_size_dict +from ...image_transforms import resize, to_channel_dimension_format +from ...image_utils import ( + IMAGENET_DEFAULT_MEAN, + IMAGENET_DEFAULT_STD, + ChannelDimension, + ImageInput, + PILImageResampling, + infer_channel_dimension_format, + is_scaled_image, + make_flat_list_of_images, + to_numpy_array, + valid_images, + validate_preprocess_arguments, +) +from ...processing_utils import ImagesKwargs +from ...utils import ( + TensorType, + filter_out_non_signature_kwargs, + is_torch_available, + is_torch_tensor, + is_vision_available, + logging, +) +from ...utils.import_utils import requires + + +if is_vision_available(): + import PIL.Image + +if is_torch_available(): + import torch + + +logger = logging.get_logger(__name__) + + +class SegformerImageProcessorKwargs(ImagesKwargs, total=False): + r""" + do_reduce_labels (`bool`, *optional*, defaults to `self.do_reduce_labels`): + Whether or not to reduce all label values of segmentation maps by 1. Usually used for datasets where 0 + is used for background, and background itself is not included in all classes of a dataset (e.g. + ADE20k). The background label will be replaced by 255. + """ + + do_reduce_labels: bool + + +@requires(backends=("vision",)) +class SegformerImageProcessor(BaseImageProcessor): + r""" + Constructs a Segformer image processor. + + Args: + do_resize (`bool`, *optional*, defaults to `True`): + Whether to resize the image's (height, width) dimensions to the specified `(size["height"], + size["width"])`. Can be overridden by the `do_resize` parameter in the `preprocess` method. + size (`dict[str, int]` *optional*, defaults to `{"height": 512, "width": 512}`): + Size of the output image after resizing. Can be overridden by the `size` parameter in the `preprocess` + method. + resample (`PILImageResampling`, *optional*, defaults to `Resampling.BILINEAR`): + Resampling filter to use if resizing the image. Can be overridden by the `resample` parameter in the + `preprocess` method. + do_rescale (`bool`, *optional*, defaults to `True`): + Whether to rescale the image by the specified scale `rescale_factor`. Can be overridden by the `do_rescale` + parameter in the `preprocess` method. + rescale_factor (`int` or `float`, *optional*, defaults to `1/255`): + Whether to normalize the image. Can be overridden by the `do_normalize` parameter in the `preprocess` + method. + do_normalize (`bool`, *optional*, defaults to `True`): + Whether to normalize the image. Can be overridden by the `do_normalize` parameter in the `preprocess` + method. + image_mean (`float` or `list[float]`, *optional*, defaults to `IMAGENET_STANDARD_MEAN`): + Mean to use if normalizing the image. This is a float or list of floats the length of the number of + channels in the image. Can be overridden by the `image_mean` parameter in the `preprocess` method. + image_std (`float` or `list[float]`, *optional*, defaults to `IMAGENET_STANDARD_STD`): + Standard deviation to use if normalizing the image. This is a float or list of floats the length of the + number of channels in the image. Can be overridden by the `image_std` parameter in the `preprocess` method. + do_reduce_labels (`bool`, *optional*, defaults to `False`): + Whether or not to reduce all label values of segmentation maps by 1. Usually used for datasets where 0 is + used for background, and background itself is not included in all classes of a dataset (e.g. ADE20k). The + background label will be replaced by 255. Can be overridden by the `do_reduce_labels` parameter in the + `preprocess` method. + """ + + model_input_names = ["pixel_values"] + valid_kwargs = SegformerImageProcessorKwargs + + @filter_out_non_signature_kwargs(extra=INIT_SERVICE_KWARGS) + def __init__( + self, + do_resize: bool = True, + size: dict[str, int] | None = None, + resample: PILImageResampling = PILImageResampling.BILINEAR, + do_rescale: bool = True, + rescale_factor: int | float = 1 / 255, + do_normalize: bool = True, + image_mean: float | list[float] | None = None, + image_std: float | list[float] | None = None, + do_reduce_labels: bool = False, + **kwargs, + ) -> None: + super().__init__(**kwargs) + size = size if size is not None else {"height": 512, "width": 512} + size = get_size_dict(size) + self.do_resize = do_resize + self.size = size + self.resample = resample + self.do_rescale = do_rescale + self.rescale_factor = rescale_factor + self.do_normalize = do_normalize + self.image_mean = image_mean if image_mean is not None else IMAGENET_DEFAULT_MEAN + self.image_std = image_std if image_std is not None else IMAGENET_DEFAULT_STD + self.do_reduce_labels = do_reduce_labels + + # Copied from transformers.models.vit.image_processing_vit.ViTImageProcessor.resize + def resize( + self, + image: np.ndarray, + size: dict[str, int], + resample: PILImageResampling = PILImageResampling.BILINEAR, + data_format: str | ChannelDimension | None = None, + input_data_format: str | ChannelDimension | None = None, + **kwargs, + ) -> np.ndarray: + """ + Resize an image to `(size["height"], size["width"])`. + + Args: + image (`np.ndarray`): + Image to resize. + size (`dict[str, int]`): + Dictionary in the format `{"height": int, "width": int}` specifying the size of the output image. + resample (`PILImageResampling`, *optional*, defaults to `PILImageResampling.BILINEAR`): + `PILImageResampling` filter to use when resizing the image e.g. `PILImageResampling.BILINEAR`. + data_format (`ChannelDimension` or `str`, *optional*): + The channel dimension format for the output image. If unset, the channel dimension format of the input + image is used. Can be one of: + - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format. + - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format. + - `"none"` or `ChannelDimension.NONE`: image in (height, width) format. + input_data_format (`ChannelDimension` or `str`, *optional*): + The channel dimension format for the input image. If unset, the channel dimension format is inferred + from the input image. Can be one of: + - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format. + - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format. + - `"none"` or `ChannelDimension.NONE`: image in (height, width) format. + + Returns: + `np.ndarray`: The resized image. + """ + size = get_size_dict(size) + if "height" not in size or "width" not in size: + raise ValueError(f"The `size` dictionary must contain the keys `height` and `width`. Got {size.keys()}") + output_size = (size["height"], size["width"]) + return resize( + image, + size=output_size, + resample=resample, + data_format=data_format, + input_data_format=input_data_format, + **kwargs, + ) + + # Copied from transformers.models.beit.image_processing_beit.BeitImageProcessor.reduce_label + def reduce_label(self, label: ImageInput) -> np.ndarray: + label = to_numpy_array(label) + # Avoid using underflow conversion + label[label == 0] = 255 + label = label - 1 + label[label == 254] = 255 + return label + + def _preprocess( + self, + image: ImageInput, + do_reduce_labels: bool, + do_resize: bool, + do_rescale: bool, + do_normalize: bool, + size: dict[str, int] | None = None, + resample: PILImageResampling | None = None, + rescale_factor: float | None = None, + image_mean: float | list[float] | None = None, + image_std: float | list[float] | None = None, + input_data_format: str | ChannelDimension | None = None, + ): + if do_reduce_labels: + image = self.reduce_label(image) + + if do_resize: + image = self.resize(image=image, size=size, resample=resample, input_data_format=input_data_format) + + if do_rescale: + image = self.rescale(image=image, scale=rescale_factor, input_data_format=input_data_format) + + if do_normalize: + image = self.normalize(image=image, mean=image_mean, std=image_std, input_data_format=input_data_format) + + return image + + def _preprocess_image( + self, + image: ImageInput, + do_resize: bool | None = None, + size: dict[str, int] | None = None, + resample: PILImageResampling | None = None, + do_rescale: bool | None = None, + rescale_factor: float | None = None, + do_normalize: bool | None = None, + image_mean: float | list[float] | None = None, + image_std: float | list[float] | None = None, + data_format: str | ChannelDimension | None = None, + input_data_format: str | ChannelDimension | None = None, + ) -> np.ndarray: + """Preprocesses a single image.""" + # All transformations expect numpy arrays. + image = to_numpy_array(image) + if do_rescale and is_scaled_image(image): + logger.warning_once( + "It looks like you are trying to rescale already rescaled images. If the input" + " images have pixel values between 0 and 1, set `do_rescale=False` to avoid rescaling them again." + ) + if input_data_format is None: + input_data_format = infer_channel_dimension_format(image) + image = self._preprocess( + image=image, + do_reduce_labels=False, + do_resize=do_resize, + size=size, + resample=resample, + do_rescale=do_rescale, + rescale_factor=rescale_factor, + do_normalize=do_normalize, + image_mean=image_mean, + image_std=image_std, + input_data_format=input_data_format, + ) + if data_format is not None: + image = to_channel_dimension_format(image, data_format, input_channel_dim=input_data_format) + return image + + def _preprocess_mask( + self, + segmentation_map: ImageInput, + do_reduce_labels: bool | None = None, + do_resize: bool | None = None, + size: dict[str, int] | None = None, + input_data_format: str | ChannelDimension | None = None, + ) -> np.ndarray: + """Preprocesses a single mask.""" + segmentation_map = to_numpy_array(segmentation_map) + # Add channel dimension if missing - needed for certain transformations + if segmentation_map.ndim == 2: + added_channel_dim = True + segmentation_map = segmentation_map[None, ...] + input_data_format = ChannelDimension.FIRST + else: + added_channel_dim = False + if input_data_format is None: + input_data_format = infer_channel_dimension_format(segmentation_map, num_channels=1) + # reduce zero label if needed + segmentation_map = self._preprocess( + image=segmentation_map, + do_reduce_labels=do_reduce_labels, + do_resize=do_resize, + resample=PILImageResampling.NEAREST, + size=size, + do_rescale=False, + do_normalize=False, + input_data_format=input_data_format, + ) + # Remove extra channel dimension if added for processing + if added_channel_dim: + segmentation_map = segmentation_map.squeeze(0) + segmentation_map = segmentation_map.astype(np.int64) + return segmentation_map + + def __call__(self, images, segmentation_maps=None, **kwargs): + """ + Preprocesses a batch of images and optionally segmentation maps. + + Overrides the `__call__` method of the `Preprocessor` class so that both images and segmentation maps can be + passed in as positional arguments. + """ + return super().__call__(images, segmentation_maps=segmentation_maps, **kwargs) + + @filter_out_non_signature_kwargs() + def preprocess( + self, + images: ImageInput, + segmentation_maps: ImageInput | None = None, + do_resize: bool | None = None, + size: dict[str, int] | None = None, + resample: PILImageResampling | None = None, + do_rescale: bool | None = None, + rescale_factor: float | None = None, + do_normalize: bool | None = None, + image_mean: float | list[float] | None = None, + image_std: float | list[float] | None = None, + do_reduce_labels: bool | None = None, + return_tensors: str | TensorType | None = None, + data_format: ChannelDimension = ChannelDimension.FIRST, + input_data_format: str | ChannelDimension | None = None, + ) -> PIL.Image.Image: + """ + Preprocess an image or batch of images. + + Args: + images (`ImageInput`): + Image to preprocess. Expects a single or batch of images with pixel values ranging from 0 to 255. If + passing in images with pixel values between 0 and 1, set `do_rescale=False`. + segmentation_maps (`ImageInput`, *optional*): + Segmentation map to preprocess. + do_resize (`bool`, *optional*, defaults to `self.do_resize`): + Whether to resize the image. + size (`dict[str, int]`, *optional*, defaults to `self.size`): + Size of the image after `resize` is applied. + resample (`int`, *optional*, defaults to `self.resample`): + Resampling filter to use if resizing the image. This can be one of the enum `PILImageResampling`, Only + has an effect if `do_resize` is set to `True`. + do_rescale (`bool`, *optional*, defaults to `self.do_rescale`): + Whether to rescale the image values between [0 - 1]. + rescale_factor (`float`, *optional*, defaults to `self.rescale_factor`): + Rescale factor to rescale the image by if `do_rescale` is set to `True`. + do_normalize (`bool`, *optional*, defaults to `self.do_normalize`): + Whether to normalize the image. + image_mean (`float` or `list[float]`, *optional*, defaults to `self.image_mean`): + Image mean. + image_std (`float` or `list[float]`, *optional*, defaults to `self.image_std`): + Image standard deviation. + do_reduce_labels (`bool`, *optional*, defaults to `self.do_reduce_labels`): + Whether or not to reduce all label values of segmentation maps by 1. Usually used for datasets where 0 + is used for background, and background itself is not included in all classes of a dataset (e.g. + ADE20k). The background label will be replaced by 255. + return_tensors (`str` or `TensorType`, *optional*): + The type of tensors to return. Can be one of: + - Unset: Return a list of `np.ndarray`. + - `TensorType.PYTORCH` or `'pt'`: Return a batch of type `torch.Tensor`. + - `TensorType.NUMPY` or `'np'`: Return a batch of type `np.ndarray`. + data_format (`ChannelDimension` or `str`, *optional*, defaults to `ChannelDimension.FIRST`): + The channel dimension format for the output image. Can be one of: + - `ChannelDimension.FIRST`: image in (num_channels, height, width) format. + - `ChannelDimension.LAST`: image in (height, width, num_channels) format. + input_data_format (`ChannelDimension` or `str`, *optional*): + The channel dimension format for the input image. If unset, the channel dimension format is inferred + from the input image. Can be one of: + - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format. + - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format. + - `"none"` or `ChannelDimension.NONE`: image in (height, width) format. + """ + do_resize = do_resize if do_resize is not None else self.do_resize + do_rescale = do_rescale if do_rescale is not None else self.do_rescale + do_normalize = do_normalize if do_normalize is not None else self.do_normalize + do_reduce_labels = do_reduce_labels if do_reduce_labels is not None else self.do_reduce_labels + resample = resample if resample is not None else self.resample + size = size if size is not None else self.size + rescale_factor = rescale_factor if rescale_factor is not None else self.rescale_factor + image_mean = image_mean if image_mean is not None else self.image_mean + image_std = image_std if image_std is not None else self.image_std + + images = make_flat_list_of_images(images) + + if segmentation_maps is not None: + segmentation_maps = make_flat_list_of_images(segmentation_maps, expected_ndims=2) + + if not valid_images(images): + raise ValueError("Invalid image type. Must be of type PIL.Image.Image, numpy.ndarray, or torch.Tensor") + validate_preprocess_arguments( + do_rescale=do_rescale, + rescale_factor=rescale_factor, + do_normalize=do_normalize, + image_mean=image_mean, + image_std=image_std, + do_resize=do_resize, + size=size, + resample=resample, + ) + + images = [ + self._preprocess_image( + image=img, + do_resize=do_resize, + resample=resample, + size=size, + do_rescale=do_rescale, + rescale_factor=rescale_factor, + do_normalize=do_normalize, + image_mean=image_mean, + image_std=image_std, + data_format=data_format, + input_data_format=input_data_format, + ) + for img in images + ] + + data = {"pixel_values": images} + + if segmentation_maps is not None: + segmentation_maps = [ + self._preprocess_mask( + segmentation_map=segmentation_map, + do_reduce_labels=do_reduce_labels, + do_resize=do_resize, + size=size, + input_data_format=input_data_format, + ) + for segmentation_map in segmentation_maps + ] + data["labels"] = segmentation_maps + + return BatchFeature(data=data, tensor_type=return_tensors) + + # Copied from transformers.models.beit.image_processing_beit.BeitImageProcessor.post_process_semantic_segmentation with Beit->Segformer + def post_process_semantic_segmentation(self, outputs, target_sizes: list[tuple] | None = None): + """ + Converts the output of [`SegformerForSemanticSegmentation`] into semantic segmentation maps. + + Args: + outputs ([`SegformerForSemanticSegmentation`]): + Raw outputs of the model. + target_sizes (`list[Tuple]` of length `batch_size`, *optional*): + List of tuples corresponding to the requested final size (height, width) of each prediction. If unset, + predictions will not be resized. + + Returns: + semantic_segmentation: `list[torch.Tensor]` of length `batch_size`, where each item is a semantic + segmentation map of shape (height, width) corresponding to the target_sizes entry (if `target_sizes` is + specified). Each entry of each `torch.Tensor` correspond to a semantic class id. + """ + logits = outputs.logits + + # Resize logits and compute semantic segmentation maps + if target_sizes is not None: + if len(logits) != len(target_sizes): + raise ValueError( + "Make sure that you pass in as many target sizes as the batch dimension of the logits" + ) + + if is_torch_tensor(target_sizes): + target_sizes = target_sizes.numpy() + + semantic_segmentation = [] + + for idx in range(len(logits)): + resized_logits = torch.nn.functional.interpolate( + logits[idx].unsqueeze(dim=0), size=target_sizes[idx], mode="bilinear", align_corners=False + ) + semantic_map = resized_logits[0].argmax(dim=0) + semantic_segmentation.append(semantic_map) + else: + semantic_segmentation = logits.argmax(dim=1) + semantic_segmentation = [semantic_segmentation[i] for i in range(semantic_segmentation.shape[0])] + + return semantic_segmentation + + +__all__ = ["SegformerImageProcessor"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/segformer/image_processing_segformer_fast.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/segformer/image_processing_segformer_fast.py new file mode 100644 index 0000000000000000000000000000000000000000..c698aeb188f0a4c1f2b40690fab0eb6640de3140 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/segformer/image_processing_segformer_fast.py @@ -0,0 +1,216 @@ +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# This file was automatically generated from src/transformers/models/segformer/modular_segformer.py. +# Do NOT edit this file manually as any edits will be overwritten by the generation of +# the file from the modular. If any change should be done, please apply the change to the +# modular_segformer.py file directly. One of our CI enforces this. +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# Copyright 2025 The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +from typing import Optional, Union + +import torch +import torchvision.transforms.v2.functional as tvF + +from ...image_processing_utils import BatchFeature +from ...image_processing_utils_fast import BaseImageProcessorFast, group_images_by_shape, reorder_images +from ...image_utils import ( + IMAGENET_DEFAULT_MEAN, + IMAGENET_DEFAULT_STD, + ChannelDimension, + ImageInput, + PILImageResampling, + SizeDict, + is_torch_tensor, +) +from ...processing_utils import Unpack +from ...utils import TensorType, auto_docstring +from .image_processing_segformer import SegformerImageProcessorKwargs + + +@auto_docstring +class SegformerImageProcessorFast(BaseImageProcessorFast): + resample = PILImageResampling.BILINEAR + image_mean = IMAGENET_DEFAULT_MEAN + image_std = IMAGENET_DEFAULT_STD + size = {"height": 512, "width": 512} + default_to_square = True + crop_size = None + do_resize = True + do_center_crop = None + do_rescale = True + do_normalize = True + do_reduce_labels = False + valid_kwargs = SegformerImageProcessorKwargs + rescale_factor = 1 / 255 + + def __init__(self, **kwargs: Unpack[SegformerImageProcessorKwargs]): + super().__init__(**kwargs) + + def reduce_label(self, labels: list["torch.Tensor"]): + for idx in range(len(labels)): + label = labels[idx] + label = torch.where(label == 0, torch.tensor(255, dtype=label.dtype), label) + label = label - 1 + label = torch.where(label == 254, torch.tensor(255, dtype=label.dtype), label) + labels[idx] = label + + return labels + + @auto_docstring + def preprocess( + self, + images: ImageInput, + segmentation_maps: ImageInput | None = None, + **kwargs: Unpack[SegformerImageProcessorKwargs], + ) -> BatchFeature: + r""" + segmentation_maps (`ImageInput`, *optional*): + The segmentation maps to preprocess. + """ + return super().preprocess(images, segmentation_maps, **kwargs) + + def _preprocess_image_like_inputs( + self, + images: ImageInput, + segmentation_maps: ImageInput | None, + do_convert_rgb: bool, + input_data_format: ChannelDimension, + device: Union[str, "torch.device"] | None = None, + **kwargs: Unpack[SegformerImageProcessorKwargs], + ) -> BatchFeature: + """ + Preprocess image-like inputs. + """ + images = self._prepare_image_like_inputs( + images=images, do_convert_rgb=do_convert_rgb, input_data_format=input_data_format, device=device + ) + images_kwargs = kwargs.copy() + images_kwargs["do_reduce_labels"] = False + batch_feature = self._preprocess(images, **images_kwargs) + + if segmentation_maps is not None: + processed_segmentation_maps = self._prepare_image_like_inputs( + images=segmentation_maps, + expected_ndims=2, + do_convert_rgb=False, + input_data_format=ChannelDimension.FIRST, + ) + + segmentation_maps_kwargs = kwargs.copy() + segmentation_maps_kwargs.update( + { + "do_normalize": False, + "do_rescale": False, + # Nearest interpolation is used for segmentation maps instead of BILINEAR. + "interpolation": tvF.InterpolationMode.NEAREST_EXACT, + } + ) + processed_segmentation_maps = self._preprocess( + images=processed_segmentation_maps, **segmentation_maps_kwargs + ).pixel_values + batch_feature["labels"] = processed_segmentation_maps.squeeze(1).to(torch.int64) + + return batch_feature + + def _preprocess( + self, + images: list["torch.Tensor"], + do_reduce_labels: bool, + interpolation: Optional["tvF.InterpolationMode"], + do_resize: bool, + do_rescale: bool, + do_normalize: bool, + size: SizeDict, + rescale_factor: float, + image_mean: float | list[float], + image_std: float | list[float], + disable_grouping: bool, + return_tensors: str | TensorType | None, + **kwargs, + ) -> BatchFeature: # Return type can be list if return_tensors=None + if do_reduce_labels: + images = self.reduce_label(images) # Apply reduction if needed + + # Group images by size for batched resizing + resized_images = images + if do_resize: + grouped_images, grouped_images_index = group_images_by_shape(images, disable_grouping=disable_grouping) + resized_images_grouped = {} + for shape, stacked_images in grouped_images.items(): + resized_stacked_images = self.resize(image=stacked_images, size=size, interpolation=interpolation) + resized_images_grouped[shape] = resized_stacked_images + resized_images = reorder_images(resized_images_grouped, grouped_images_index) + + # Group images by size for further processing (rescale/normalize) + # Needed in case do_resize is False, or resize returns images with different sizes + grouped_images, grouped_images_index = group_images_by_shape(resized_images, disable_grouping=disable_grouping) + processed_images_grouped = {} + for shape, stacked_images in grouped_images.items(): + # Fused rescale and normalize + stacked_images = self.rescale_and_normalize( + stacked_images, do_rescale, rescale_factor, do_normalize, image_mean, image_std + ) + processed_images_grouped[shape] = stacked_images + + processed_images = reorder_images(processed_images_grouped, grouped_images_index) + + # Stack images into a single tensor if return_tensors is set + + return BatchFeature(data={"pixel_values": processed_images}, tensor_type=return_tensors) + + def post_process_semantic_segmentation(self, outputs, target_sizes: list[tuple] | None = None): + """ + Converts the output of [`SegformerForSemanticSegmentation`] into semantic segmentation maps. + + Args: + outputs ([`SegformerForSemanticSegmentation`]): + Raw outputs of the model. + target_sizes (`list[Tuple]` of length `batch_size`, *optional*): + List of tuples corresponding to the requested final size (height, width) of each prediction. If unset, + predictions will not be resized. + + Returns: + semantic_segmentation: `list[torch.Tensor]` of length `batch_size`, where each item is a semantic + segmentation map of shape (height, width) corresponding to the target_sizes entry (if `target_sizes` is + specified). Each entry of each `torch.Tensor` correspond to a semantic class id. + """ + logits = outputs.logits + + # Resize logits and compute semantic segmentation maps + if target_sizes is not None: + if len(logits) != len(target_sizes): + raise ValueError( + "Make sure that you pass in as many target sizes as the batch dimension of the logits" + ) + + if is_torch_tensor(target_sizes): + target_sizes = target_sizes.numpy() + + semantic_segmentation = [] + + for idx in range(len(logits)): + resized_logits = torch.nn.functional.interpolate( + logits[idx].unsqueeze(dim=0), size=target_sizes[idx], mode="bilinear", align_corners=False + ) + semantic_map = resized_logits[0].argmax(dim=0) + semantic_segmentation.append(semantic_map) + else: + semantic_segmentation = logits.argmax(dim=1) + semantic_segmentation = [semantic_segmentation[i] for i in range(semantic_segmentation.shape[0])] + + return semantic_segmentation + + +__all__ = ["SegformerImageProcessorFast"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/segformer/modeling_segformer.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/segformer/modeling_segformer.py new file mode 100644 index 0000000000000000000000000000000000000000..0a5c2a13515dd6c6b1f2d2e0473ea9f32bed3c81 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/segformer/modeling_segformer.py @@ -0,0 +1,714 @@ +# Copyright 2021 NVIDIA The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""PyTorch SegFormer model.""" + +import math + +import torch +from torch import nn +from torch.nn import BCEWithLogitsLoss, CrossEntropyLoss + +from ...activations import ACT2FN +from ...modeling_outputs import BaseModelOutput, ImageClassifierOutput, SemanticSegmenterOutput +from ...modeling_utils import PreTrainedModel +from ...utils import auto_docstring, logging +from .configuration_segformer import SegformerConfig + + +logger = logging.get_logger(__name__) + + +class SegFormerImageClassifierOutput(ImageClassifierOutput): + """ + Base class for outputs of image classification models. + + Args: + loss (`torch.FloatTensor` of shape `(1,)`, *optional*, returned when `labels` is provided): + Classification (or regression if config.num_labels==1) loss. + logits (`torch.FloatTensor` of shape `(batch_size, config.num_labels)`): + Classification (or regression if config.num_labels==1) scores (before SoftMax). + hidden_states (`tuple(torch.FloatTensor)`, *optional*, returned when `output_hidden_states=True` is passed or when `config.output_hidden_states=True`): + Tuple of `torch.FloatTensor` (one for the output of the embeddings, if the model has an embedding layer, + + one for the output of each stage) of shape `(batch_size, num_channels, height, width)`. Hidden-states (also + called feature maps) of the model at the output of each stage. + attentions (`tuple(torch.FloatTensor)`, *optional*, returned when `output_attentions=True` is passed or when `config.output_attentions=True`): + Tuple of `torch.FloatTensor` (one for each layer) of shape `(batch_size, num_heads, patch_size, + sequence_length)`. + + Attentions weights after the attention softmax, used to compute the weighted average in the self-attention + heads. + """ + + loss: torch.FloatTensor | None = None + logits: torch.FloatTensor | None = None + hidden_states: tuple[torch.FloatTensor] | None = None + attentions: tuple[torch.FloatTensor] | None = None + + +# Copied from transformers.models.beit.modeling_beit.drop_path +def drop_path(input: torch.Tensor, drop_prob: float = 0.0, training: bool = False) -> torch.Tensor: + """ + Drop paths (Stochastic Depth) per sample (when applied in main path of residual blocks). + + """ + if drop_prob == 0.0 or not training: + return input + keep_prob = 1 - drop_prob + shape = (input.shape[0],) + (1,) * (input.ndim - 1) # work with diff dim tensors, not just 2D ConvNets + random_tensor = keep_prob + torch.rand(shape, dtype=input.dtype, device=input.device) + random_tensor.floor_() # binarize + output = input.div(keep_prob) * random_tensor + return output + + +# Copied from transformers.models.convnext.modeling_convnext.ConvNextDropPath with ConvNext->Segformer +class SegformerDropPath(nn.Module): + """Drop paths (Stochastic Depth) per sample (when applied in main path of residual blocks).""" + + def __init__(self, drop_prob: float | None = None) -> None: + super().__init__() + self.drop_prob = drop_prob + + def forward(self, hidden_states: torch.Tensor) -> torch.Tensor: + return drop_path(hidden_states, self.drop_prob, self.training) + + def extra_repr(self) -> str: + return f"p={self.drop_prob}" + + +class SegformerOverlapPatchEmbeddings(nn.Module): + """Construct the overlapping patch embeddings.""" + + def __init__(self, patch_size, stride, num_channels, hidden_size): + super().__init__() + self.proj = nn.Conv2d( + num_channels, + hidden_size, + kernel_size=patch_size, + stride=stride, + padding=patch_size // 2, + ) + + self.layer_norm = nn.LayerNorm(hidden_size) + + def forward(self, pixel_values): + embeddings = self.proj(pixel_values) + _, _, height, width = embeddings.shape + # (batch_size, num_channels, height, width) -> (batch_size, num_channels, height*width) -> (batch_size, height*width, num_channels) + # this can be fed to a Transformer layer + embeddings = embeddings.flatten(2).transpose(1, 2) + embeddings = self.layer_norm(embeddings) + return embeddings, height, width + + +class SegformerEfficientSelfAttention(nn.Module): + """SegFormer's efficient self-attention mechanism. Employs the sequence reduction process introduced in the [PvT + paper](https://huggingface.co/papers/2102.12122).""" + + def __init__(self, config, hidden_size, num_attention_heads, sequence_reduction_ratio): + super().__init__() + self.hidden_size = hidden_size + self.num_attention_heads = num_attention_heads + + if self.hidden_size % self.num_attention_heads != 0: + raise ValueError( + f"The hidden size ({self.hidden_size}) is not a multiple of the number of attention " + f"heads ({self.num_attention_heads})" + ) + + self.attention_head_size = int(self.hidden_size / self.num_attention_heads) + self.all_head_size = self.num_attention_heads * self.attention_head_size + + self.query = nn.Linear(self.hidden_size, self.all_head_size) + self.key = nn.Linear(self.hidden_size, self.all_head_size) + self.value = nn.Linear(self.hidden_size, self.all_head_size) + + self.dropout = nn.Dropout(config.attention_probs_dropout_prob) + + self.sr_ratio = sequence_reduction_ratio + if sequence_reduction_ratio > 1: + self.sr = nn.Conv2d( + hidden_size, hidden_size, kernel_size=sequence_reduction_ratio, stride=sequence_reduction_ratio + ) + self.layer_norm = nn.LayerNorm(hidden_size) + + def forward( + self, + hidden_states, + height, + width, + output_attentions=False, + ): + batch_size, seq_length, _ = hidden_states.shape + query_layer = ( + self.query(hidden_states) + .view(batch_size, -1, self.num_attention_heads, self.attention_head_size) + .transpose(1, 2) + ) + + if self.sr_ratio > 1: + batch_size, seq_len, num_channels = hidden_states.shape + # Reshape to (batch_size, num_channels, height, width) + hidden_states = hidden_states.permute(0, 2, 1).reshape(batch_size, num_channels, height, width) + # Apply sequence reduction + hidden_states = self.sr(hidden_states) + # Reshape back to (batch_size, seq_len, num_channels) + hidden_states = hidden_states.reshape(batch_size, num_channels, -1).permute(0, 2, 1) + hidden_states = self.layer_norm(hidden_states) + + key_layer = ( + self.key(hidden_states) + .view(batch_size, -1, self.num_attention_heads, self.attention_head_size) + .transpose(1, 2) + ) + value_layer = ( + self.value(hidden_states) + .view(batch_size, -1, self.num_attention_heads, self.attention_head_size) + .transpose(1, 2) + ) + + # Take the dot product between "query" and "key" to get the raw attention scores. + attention_scores = torch.matmul(query_layer, key_layer.transpose(-1, -2)) + + attention_scores = attention_scores / math.sqrt(self.attention_head_size) + + # Normalize the attention scores to probabilities. + attention_probs = nn.functional.softmax(attention_scores, dim=-1) + + # This is actually dropping out entire tokens to attend to, which might + # seem a bit unusual, but is taken from the original Transformer paper. + attention_probs = self.dropout(attention_probs) + + context_layer = torch.matmul(attention_probs, value_layer) + + context_layer = context_layer.permute(0, 2, 1, 3).contiguous() + new_context_layer_shape = context_layer.size()[:-2] + (self.all_head_size,) + context_layer = context_layer.view(new_context_layer_shape) + + outputs = (context_layer, attention_probs) if output_attentions else (context_layer,) + + return outputs + + +class SegformerSelfOutput(nn.Module): + def __init__(self, config, hidden_size): + super().__init__() + self.dense = nn.Linear(hidden_size, hidden_size) + self.dropout = nn.Dropout(config.hidden_dropout_prob) + + def forward(self, hidden_states, input_tensor): + hidden_states = self.dense(hidden_states) + hidden_states = self.dropout(hidden_states) + return hidden_states + + +class SegformerAttention(nn.Module): + def __init__(self, config, hidden_size, num_attention_heads, sequence_reduction_ratio): + super().__init__() + self.self = SegformerEfficientSelfAttention( + config=config, + hidden_size=hidden_size, + num_attention_heads=num_attention_heads, + sequence_reduction_ratio=sequence_reduction_ratio, + ) + self.output = SegformerSelfOutput(config, hidden_size=hidden_size) + + def forward(self, hidden_states, height, width, output_attentions=False): + self_outputs = self.self(hidden_states, height, width, output_attentions) + + attention_output = self.output(self_outputs[0], hidden_states) + outputs = (attention_output,) + self_outputs[1:] # add attentions if we output them + return outputs + + +class SegformerDWConv(nn.Module): + def __init__(self, dim=768): + super().__init__() + self.dwconv = nn.Conv2d(dim, dim, 3, 1, 1, bias=True, groups=dim) + + def forward(self, hidden_states, height, width): + batch_size, seq_len, num_channels = hidden_states.shape + hidden_states = hidden_states.transpose(1, 2).view(batch_size, num_channels, height, width) + hidden_states = self.dwconv(hidden_states) + hidden_states = hidden_states.flatten(2).transpose(1, 2) + + return hidden_states + + +class SegformerMixFFN(nn.Module): + def __init__(self, config, in_features, hidden_features=None, out_features=None): + super().__init__() + out_features = out_features or in_features + self.dense1 = nn.Linear(in_features, hidden_features) + self.dwconv = SegformerDWConv(hidden_features) + if isinstance(config.hidden_act, str): + self.intermediate_act_fn = ACT2FN[config.hidden_act] + else: + self.intermediate_act_fn = config.hidden_act + self.dense2 = nn.Linear(hidden_features, out_features) + self.dropout = nn.Dropout(config.hidden_dropout_prob) + + def forward(self, hidden_states, height, width): + hidden_states = self.dense1(hidden_states) + hidden_states = self.dwconv(hidden_states, height, width) + hidden_states = self.intermediate_act_fn(hidden_states) + hidden_states = self.dropout(hidden_states) + hidden_states = self.dense2(hidden_states) + hidden_states = self.dropout(hidden_states) + return hidden_states + + +class SegformerLayer(nn.Module): + """This corresponds to the Block class in the original implementation.""" + + def __init__(self, config, hidden_size, num_attention_heads, drop_path, sequence_reduction_ratio, mlp_ratio): + super().__init__() + self.layer_norm_1 = nn.LayerNorm(hidden_size) + self.attention = SegformerAttention( + config, + hidden_size=hidden_size, + num_attention_heads=num_attention_heads, + sequence_reduction_ratio=sequence_reduction_ratio, + ) + self.drop_path = SegformerDropPath(drop_path) if drop_path > 0.0 else nn.Identity() + self.layer_norm_2 = nn.LayerNorm(hidden_size) + mlp_hidden_size = int(hidden_size * mlp_ratio) + self.mlp = SegformerMixFFN(config, in_features=hidden_size, hidden_features=mlp_hidden_size) + + def forward(self, hidden_states, height, width, output_attentions=False): + self_attention_outputs = self.attention( + self.layer_norm_1(hidden_states), # in Segformer, layernorm is applied before self-attention + height, + width, + output_attentions=output_attentions, + ) + + attention_output = self_attention_outputs[0] + outputs = self_attention_outputs[1:] # add self attentions if we output attention weights + + # first residual connection (with stochastic depth) + attention_output = self.drop_path(attention_output) + hidden_states = attention_output + hidden_states + + mlp_output = self.mlp(self.layer_norm_2(hidden_states), height, width) + + # second residual connection (with stochastic depth) + mlp_output = self.drop_path(mlp_output) + layer_output = mlp_output + hidden_states + + outputs = (layer_output,) + outputs + + return outputs + + +class SegformerEncoder(nn.Module): + def __init__(self, config): + super().__init__() + self.config = config + + # stochastic depth decay rule + drop_path_decays = [ + x.item() for x in torch.linspace(0, config.drop_path_rate, sum(config.depths), device="cpu") + ] + + # patch embeddings + embeddings = [] + for i in range(config.num_encoder_blocks): + embeddings.append( + SegformerOverlapPatchEmbeddings( + patch_size=config.patch_sizes[i], + stride=config.strides[i], + num_channels=config.num_channels if i == 0 else config.hidden_sizes[i - 1], + hidden_size=config.hidden_sizes[i], + ) + ) + self.patch_embeddings = nn.ModuleList(embeddings) + + # Transformer blocks + blocks = [] + cur = 0 + for i in range(config.num_encoder_blocks): + # each block consists of layers + layers = [] + if i != 0: + cur += config.depths[i - 1] + for j in range(config.depths[i]): + layers.append( + SegformerLayer( + config, + hidden_size=config.hidden_sizes[i], + num_attention_heads=config.num_attention_heads[i], + drop_path=drop_path_decays[cur + j], + sequence_reduction_ratio=config.sr_ratios[i], + mlp_ratio=config.mlp_ratios[i], + ) + ) + blocks.append(nn.ModuleList(layers)) + + self.block = nn.ModuleList(blocks) + + # Layer norms + self.layer_norm = nn.ModuleList( + [nn.LayerNorm(config.hidden_sizes[i]) for i in range(config.num_encoder_blocks)] + ) + + def forward( + self, + pixel_values: torch.FloatTensor, + output_attentions: bool | None = False, + output_hidden_states: bool | None = False, + return_dict: bool | None = True, + ) -> tuple | BaseModelOutput: + all_hidden_states = () if output_hidden_states else None + all_self_attentions = () if output_attentions else None + + batch_size = pixel_values.shape[0] + + hidden_states = pixel_values + for idx, x in enumerate(zip(self.patch_embeddings, self.block, self.layer_norm)): + embedding_layer, block_layer, norm_layer = x + # first, obtain patch embeddings + hidden_states, height, width = embedding_layer(hidden_states) + # second, send embeddings through blocks + for i, blk in enumerate(block_layer): + layer_outputs = blk(hidden_states, height, width, output_attentions) + hidden_states = layer_outputs[0] + if output_attentions: + all_self_attentions = all_self_attentions + (layer_outputs[1],) + # third, apply layer norm + hidden_states = norm_layer(hidden_states) + # fourth, optionally reshape back to (batch_size, num_channels, height, width) + if idx != len(self.patch_embeddings) - 1 or ( + idx == len(self.patch_embeddings) - 1 and self.config.reshape_last_stage + ): + hidden_states = hidden_states.reshape(batch_size, height, width, -1).permute(0, 3, 1, 2).contiguous() + if output_hidden_states: + all_hidden_states = all_hidden_states + (hidden_states,) + + if not return_dict: + return tuple(v for v in [hidden_states, all_hidden_states, all_self_attentions] if v is not None) + return BaseModelOutput( + last_hidden_state=hidden_states, + hidden_states=all_hidden_states, + attentions=all_self_attentions, + ) + + +@auto_docstring +class SegformerPreTrainedModel(PreTrainedModel): + config: SegformerConfig + base_model_prefix = "segformer" + main_input_name = "pixel_values" + input_modalities = ("image",) + + +@auto_docstring +class SegformerModel(SegformerPreTrainedModel): + def __init__(self, config): + super().__init__(config) + self.config = config + + # hierarchical Transformer encoder + self.encoder = SegformerEncoder(config) + + # Initialize weights and apply final processing + self.post_init() + + @auto_docstring + def forward( + self, + pixel_values: torch.FloatTensor, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + **kwargs, + ) -> tuple | BaseModelOutput: + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + encoder_outputs = self.encoder( + pixel_values, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + sequence_output = encoder_outputs[0] + + if not return_dict: + return (sequence_output,) + encoder_outputs[1:] + + return BaseModelOutput( + last_hidden_state=sequence_output, + hidden_states=encoder_outputs.hidden_states, + attentions=encoder_outputs.attentions, + ) + + +@auto_docstring( + custom_intro=""" + SegFormer Model transformer with an image classification head on top (a linear layer on top of the final hidden + states) e.g. for ImageNet. + """ +) +class SegformerForImageClassification(SegformerPreTrainedModel): + def __init__(self, config): + super().__init__(config) + + self.num_labels = config.num_labels + self.segformer = SegformerModel(config) + + # Classifier head + self.classifier = nn.Linear(config.hidden_sizes[-1], config.num_labels) + + # Initialize weights and apply final processing + self.post_init() + + @auto_docstring + def forward( + self, + pixel_values: torch.FloatTensor | None = None, + labels: torch.LongTensor | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + **kwargs, + ) -> tuple | SegFormerImageClassifierOutput: + r""" + labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*): + Labels for computing the image classification/regression loss. Indices should be in `[0, ..., + config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If + `config.num_labels > 1` a classification loss is computed (Cross-Entropy). + """ + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + outputs = self.segformer( + pixel_values, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + + sequence_output = outputs[0] + + # convert last hidden states to (batch_size, height*width, hidden_size) + batch_size = sequence_output.shape[0] + if self.config.reshape_last_stage: + # (batch_size, num_channels, height, width) -> (batch_size, height, width, num_channels) + sequence_output = sequence_output.permute(0, 2, 3, 1) + sequence_output = sequence_output.reshape(batch_size, -1, self.config.hidden_sizes[-1]) + + # global average pooling + sequence_output = sequence_output.mean(dim=1) + + logits = self.classifier(sequence_output) + + loss = None + if labels is not None: + loss = self.loss_function(labels, logits, self.config) + + if not return_dict: + output = (logits,) + outputs[1:] + return ((loss,) + output) if loss is not None else output + + return SegFormerImageClassifierOutput( + loss=loss, + logits=logits, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + ) + + +class SegformerMLP(nn.Module): + """ + Linear Embedding. + """ + + def __init__(self, config: SegformerConfig, input_dim): + super().__init__() + self.proj = nn.Linear(input_dim, config.decoder_hidden_size) + + def forward(self, hidden_states: torch.Tensor): + hidden_states = hidden_states.flatten(2).transpose(1, 2) + hidden_states = self.proj(hidden_states) + return hidden_states + + +class SegformerDecodeHead(nn.Module): + def __init__(self, config): + super().__init__() + # linear layers which will unify the channel dimension of each of the encoder blocks to the same config.decoder_hidden_size + mlps = [] + for i in range(config.num_encoder_blocks): + mlp = SegformerMLP(config, input_dim=config.hidden_sizes[i]) + mlps.append(mlp) + self.linear_c = nn.ModuleList(mlps) + + # the following 3 layers implement the ConvModule of the original implementation + self.linear_fuse = nn.Conv2d( + in_channels=config.decoder_hidden_size * config.num_encoder_blocks, + out_channels=config.decoder_hidden_size, + kernel_size=1, + bias=False, + ) + self.batch_norm = nn.BatchNorm2d(config.decoder_hidden_size) + self.activation = nn.ReLU() + + self.dropout = nn.Dropout(config.classifier_dropout_prob) + self.classifier = nn.Conv2d(config.decoder_hidden_size, config.num_labels, kernel_size=1) + + self.config = config + + def forward(self, encoder_hidden_states: torch.FloatTensor, **kwargs) -> torch.Tensor: + batch_size = encoder_hidden_states[-1].shape[0] + + all_hidden_states = () + for encoder_hidden_state, mlp in zip(encoder_hidden_states, self.linear_c): + if self.config.reshape_last_stage is False and encoder_hidden_state.ndim == 3: + height = width = int(math.sqrt(encoder_hidden_state.shape[-1])) + encoder_hidden_state = ( + encoder_hidden_state.reshape(batch_size, height, width, -1).permute(0, 3, 1, 2).contiguous() + ) + + # unify channel dimension + height, width = encoder_hidden_state.shape[2], encoder_hidden_state.shape[3] + encoder_hidden_state = mlp(encoder_hidden_state) + encoder_hidden_state = encoder_hidden_state.permute(0, 2, 1) + encoder_hidden_state = encoder_hidden_state.reshape(batch_size, -1, height, width) + # upsample + encoder_hidden_state = nn.functional.interpolate( + encoder_hidden_state, size=encoder_hidden_states[0].size()[2:], mode="bilinear", align_corners=False + ) + all_hidden_states += (encoder_hidden_state,) + + hidden_states = self.linear_fuse(torch.cat(all_hidden_states[::-1], dim=1)) + hidden_states = self.batch_norm(hidden_states) + hidden_states = self.activation(hidden_states) + hidden_states = self.dropout(hidden_states) + + # logits are of shape (batch_size, num_labels, height/4, width/4) + logits = self.classifier(hidden_states) + + return logits + + +@auto_docstring( + custom_intro=""" + SegFormer Model transformer with an all-MLP decode head on top e.g. for ADE20k, CityScapes. + """ +) +class SegformerForSemanticSegmentation(SegformerPreTrainedModel): + def __init__(self, config): + super().__init__(config) + self.segformer = SegformerModel(config) + self.decode_head = SegformerDecodeHead(config) + + # Initialize weights and apply final processing + self.post_init() + + @auto_docstring + def forward( + self, + pixel_values: torch.FloatTensor, + labels: torch.LongTensor | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + **kwargs, + ) -> tuple | SemanticSegmenterOutput: + r""" + labels (`torch.LongTensor` of shape `(batch_size, height, width)`, *optional*): + Ground truth semantic segmentation maps for computing the loss. Indices should be in `[0, ..., + config.num_labels - 1]`. If `config.num_labels > 1`, a classification loss is computed (Cross-Entropy). + + Examples: + + ```python + >>> from transformers import AutoImageProcessor, SegformerForSemanticSegmentation + >>> from PIL import Image + >>> import httpx + >>> from io import BytesIO + + >>> image_processor = AutoImageProcessor.from_pretrained("nvidia/segformer-b0-finetuned-ade-512-512") + >>> model = SegformerForSemanticSegmentation.from_pretrained("nvidia/segformer-b0-finetuned-ade-512-512") + + >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg" + >>> with httpx.stream("GET", url) as response: + ... image = Image.open(BytesIO(response.read())) + + >>> inputs = image_processor(images=image, return_tensors="pt") + >>> outputs = model(**inputs) + >>> logits = outputs.logits # shape (batch_size, num_labels, height/4, width/4) + >>> list(logits.shape) + [1, 150, 128, 128] + ```""" + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + + if labels is not None and self.config.num_labels < 1: + raise ValueError(f"Number of labels should be >=0: {self.config.num_labels}") + + outputs = self.segformer( + pixel_values, + output_attentions=output_attentions, + output_hidden_states=True, # we need the intermediate hidden states + return_dict=return_dict, + ) + + encoder_hidden_states = outputs.hidden_states if return_dict else outputs[1] + + logits = self.decode_head(encoder_hidden_states) + + loss = None + if labels is not None: + # upsample logits to the images' original size + upsampled_logits = nn.functional.interpolate( + logits, size=labels.shape[-2:], mode="bilinear", align_corners=False + ) + if self.config.num_labels > 1: + loss_fct = CrossEntropyLoss(ignore_index=self.config.semantic_loss_ignore_index) + loss = loss_fct(upsampled_logits, labels) + elif self.config.num_labels == 1: + valid_mask = ((labels >= 0) & (labels != self.config.semantic_loss_ignore_index)).float() + loss_fct = BCEWithLogitsLoss(reduction="none") + loss = loss_fct(upsampled_logits.squeeze(1), labels.float()) + loss = (loss * valid_mask).mean() + + if not return_dict: + if output_hidden_states: + output = (logits,) + outputs[1:] + else: + output = (logits,) + outputs[2:] + return ((loss,) + output) if loss is not None else output + + return SemanticSegmenterOutput( + loss=loss, + logits=logits, + hidden_states=outputs.hidden_states if output_hidden_states else None, + attentions=outputs.attentions, + ) + + +__all__ = [ + "SegformerDecodeHead", + "SegformerForImageClassification", + "SegformerForSemanticSegmentation", + "SegformerLayer", + "SegformerModel", + "SegformerPreTrainedModel", +] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/segformer/modular_segformer.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/segformer/modular_segformer.py new file mode 100644 index 0000000000000000000000000000000000000000..51296fb79fa082aa58d35a5ac8884e822278aa4e --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/segformer/modular_segformer.py @@ -0,0 +1,146 @@ +# Copyright 2025 The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""Fast Image processor class for Segformer.""" + +from typing import Optional, Union + +import torch +import torchvision.transforms.v2.functional as tvF + +from transformers.models.beit.image_processing_beit_fast import BeitImageProcessorFast + +from ...image_processing_utils import BatchFeature +from ...image_processing_utils_fast import ( + group_images_by_shape, + reorder_images, +) +from ...image_utils import ( + IMAGENET_DEFAULT_MEAN, + IMAGENET_DEFAULT_STD, + ChannelDimension, + ImageInput, + PILImageResampling, + SizeDict, +) +from ...processing_utils import Unpack +from ...utils import ( + TensorType, +) +from .image_processing_segformer import SegformerImageProcessorKwargs + + +class SegformerImageProcessorFast(BeitImageProcessorFast): + resample = PILImageResampling.BILINEAR + image_mean = IMAGENET_DEFAULT_MEAN + image_std = IMAGENET_DEFAULT_STD + size = {"height": 512, "width": 512} + do_resize = True + do_rescale = True + rescale_factor = 1 / 255 + do_normalize = True + do_reduce_labels = False + do_center_crop = None + crop_size = None + + def _preprocess_image_like_inputs( + self, + images: ImageInput, + segmentation_maps: ImageInput | None, + do_convert_rgb: bool, + input_data_format: ChannelDimension, + device: Union[str, "torch.device"] | None = None, + **kwargs: Unpack[SegformerImageProcessorKwargs], + ) -> BatchFeature: + """ + Preprocess image-like inputs. + """ + images = self._prepare_image_like_inputs( + images=images, do_convert_rgb=do_convert_rgb, input_data_format=input_data_format, device=device + ) + images_kwargs = kwargs.copy() + images_kwargs["do_reduce_labels"] = False + batch_feature = self._preprocess(images, **images_kwargs) + + if segmentation_maps is not None: + processed_segmentation_maps = self._prepare_image_like_inputs( + images=segmentation_maps, + expected_ndims=2, + do_convert_rgb=False, + input_data_format=ChannelDimension.FIRST, + ) + + segmentation_maps_kwargs = kwargs.copy() + segmentation_maps_kwargs.update( + { + "do_normalize": False, + "do_rescale": False, + # Nearest interpolation is used for segmentation maps instead of BILINEAR. + "interpolation": tvF.InterpolationMode.NEAREST_EXACT, + } + ) + processed_segmentation_maps = self._preprocess( + images=processed_segmentation_maps, **segmentation_maps_kwargs + ).pixel_values + batch_feature["labels"] = processed_segmentation_maps.squeeze(1).to(torch.int64) + + return batch_feature + + def _preprocess( + self, + images: list["torch.Tensor"], + do_reduce_labels: bool, + interpolation: Optional["tvF.InterpolationMode"], + do_resize: bool, + do_rescale: bool, + do_normalize: bool, + size: SizeDict, + rescale_factor: float, + image_mean: float | list[float], + image_std: float | list[float], + disable_grouping: bool, + return_tensors: str | TensorType | None, + **kwargs, + ) -> BatchFeature: # Return type can be list if return_tensors=None + if do_reduce_labels: + images = self.reduce_label(images) # Apply reduction if needed + + # Group images by size for batched resizing + resized_images = images + if do_resize: + grouped_images, grouped_images_index = group_images_by_shape(images, disable_grouping=disable_grouping) + resized_images_grouped = {} + for shape, stacked_images in grouped_images.items(): + resized_stacked_images = self.resize(image=stacked_images, size=size, interpolation=interpolation) + resized_images_grouped[shape] = resized_stacked_images + resized_images = reorder_images(resized_images_grouped, grouped_images_index) + + # Group images by size for further processing (rescale/normalize) + # Needed in case do_resize is False, or resize returns images with different sizes + grouped_images, grouped_images_index = group_images_by_shape(resized_images, disable_grouping=disable_grouping) + processed_images_grouped = {} + for shape, stacked_images in grouped_images.items(): + # Fused rescale and normalize + stacked_images = self.rescale_and_normalize( + stacked_images, do_rescale, rescale_factor, do_normalize, image_mean, image_std + ) + processed_images_grouped[shape] = stacked_images + + processed_images = reorder_images(processed_images_grouped, grouped_images_index) + + # Stack images into a single tensor if return_tensors is set + + return BatchFeature(data={"pixel_values": processed_images}, tensor_type=return_tensors) + + +__all__ = ["SegformerImageProcessorFast"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/seggpt/__init__.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/seggpt/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..ec646f2f81a21d50d50b67177638d275427bc42b --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/seggpt/__init__.py @@ -0,0 +1,28 @@ +# Copyright 2024 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from typing import TYPE_CHECKING + +from ...utils import _LazyModule +from ...utils.import_utils import define_import_structure + + +if TYPE_CHECKING: + from .configuration_seggpt import * + from .image_processing_seggpt import * + from .modeling_seggpt import * +else: + import sys + + _file = globals()["__file__"] + sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__) diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/seggpt/configuration_seggpt.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/seggpt/configuration_seggpt.py new file mode 100644 index 0000000000000000000000000000000000000000..85a6e9ada8844510627930f6ccfb1a70170b9c40 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/seggpt/configuration_seggpt.py @@ -0,0 +1,142 @@ +# Copyright 2024 The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""SegGpt model configuration""" + +from ...configuration_utils import PreTrainedConfig +from ...utils import logging + + +logger = logging.get_logger(__name__) + + +class SegGptConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`SegGptModel`]. It is used to instantiate a SegGPT + model according to the specified arguments, defining the model architecture. Instantiating a configuration with the + defaults will yield a similar configuration to that of the SegGPT + [BAAI/seggpt-vit-large](https://huggingface.co/BAAI/seggpt-vit-large) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + hidden_size (`int`, *optional*, defaults to 1024): + Dimensionality of the encoder layers and the pooler layer. + num_hidden_layers (`int`, *optional*, defaults to 24): + Number of hidden layers in the Transformer encoder. + num_attention_heads (`int`, *optional*, defaults to 16): + Number of attention heads for each attention layer in the Transformer encoder. + hidden_act (`str` or `function`, *optional*, defaults to `"gelu"`): + The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`, + `"relu"`, `"selu"` and `"gelu_new"` are supported. + hidden_dropout_prob (`float`, *optional*, defaults to 0.0): + The dropout probability for all fully connected layers in the embeddings, encoder, and pooler. + initializer_range (`float`, *optional*, defaults to 0.02): + The standard deviation of the truncated_normal_initializer for initializing all weight matrices. + layer_norm_eps (`float`, *optional*, defaults to 1e-06): + The epsilon used by the layer normalization layers. + image_size (`list[int]`, *optional*, defaults to `[896, 448]`): + The size (resolution) of each image. + patch_size (`int`, *optional*, defaults to 16): + The size (resolution) of each patch. + num_channels (`int`, *optional*, defaults to 3): + The number of input channels. + qkv_bias (`bool`, *optional*, defaults to `True`): + Whether to add a bias to the queries, keys and values. + mlp_dim (`int`, *optional*): + The dimensionality of the MLP layer in the Transformer encoder. If unset, defaults to + `hidden_size` * 4. + drop_path_rate (`float`, *optional*, defaults to 0.1): + The drop path rate for the dropout layers. + pretrain_image_size (`int`, *optional*, defaults to 224): + The pretrained size of the absolute position embeddings. + decoder_hidden_size (`int`, *optional*, defaults to 64): + Hidden size for decoder. + use_relative_position_embeddings (`bool`, *optional*, defaults to `True`): + Whether to use relative position embeddings in the attention layers. + merge_index (`int`, *optional*, defaults to 2): + The index of the encoder layer to merge the embeddings. + intermediate_hidden_state_indices (`list[int]`, *optional*, defaults to `[5, 11, 17, 23]`): + The indices of the encoder layers which we store as features for the decoder. + beta (`float`, *optional*, defaults to 0.01): + Regularization factor for SegGptLoss (smooth-l1 loss). + + Example: + + ```python + >>> from transformers import SegGptConfig, SegGptModel + + >>> # Initializing a SegGPT seggpt-vit-large style configuration + >>> configuration = SegGptConfig() + + >>> # Initializing a model (with random weights) from the seggpt-vit-large style configuration + >>> model = SegGptModel(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "seggpt" + + def __init__( + self, + hidden_size=1024, + num_hidden_layers=24, + num_attention_heads=16, + hidden_act="gelu", + hidden_dropout_prob=0.0, + initializer_range=0.02, + layer_norm_eps=1e-6, + image_size=[896, 448], + patch_size=16, + num_channels=3, + qkv_bias=True, + mlp_dim=None, + drop_path_rate=0.1, + pretrain_image_size=224, + decoder_hidden_size=64, + use_relative_position_embeddings=True, + merge_index=2, + intermediate_hidden_state_indices=[5, 11, 17, 23], + beta=0.01, + **kwargs, + ): + super().__init__(**kwargs) + + if merge_index > min(intermediate_hidden_state_indices): + raise ValueError( + f"Merge index must be less than the minimum encoder output index, but got {merge_index=} and {intermediate_hidden_state_indices=}" + ) + self.hidden_size = hidden_size + self.num_hidden_layers = num_hidden_layers + self.num_attention_heads = num_attention_heads + self.hidden_act = hidden_act + self.hidden_dropout_prob = hidden_dropout_prob + self.initializer_range = initializer_range + self.layer_norm_eps = layer_norm_eps + self.image_size = image_size + self.patch_size = patch_size + self.num_channels = num_channels + self.qkv_bias = qkv_bias + self.drop_path_rate = drop_path_rate + self.pretrain_image_size = pretrain_image_size + self.decoder_hidden_size = decoder_hidden_size + self.use_relative_position_embeddings = use_relative_position_embeddings + self.merge_index = merge_index + self.intermediate_hidden_state_indices = intermediate_hidden_state_indices + self.beta = beta + self.mlp_dim = int(hidden_size * 4) if mlp_dim is None else mlp_dim + + +__all__ = ["SegGptConfig"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/seggpt/image_processing_seggpt.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/seggpt/image_processing_seggpt.py new file mode 100644 index 0000000000000000000000000000000000000000..fccb00f9c428f9f2df1295d6facb512be80379b1 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/seggpt/image_processing_seggpt.py @@ -0,0 +1,605 @@ +# Copyright 2024 The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""Image processor class for SegGPT.""" + +import numpy as np + +from ...image_processing_utils import BaseImageProcessor, BatchFeature, get_size_dict +from ...image_transforms import resize, to_channel_dimension_format +from ...image_utils import ( + IMAGENET_DEFAULT_MEAN, + IMAGENET_DEFAULT_STD, + ChannelDimension, + ImageInput, + PILImageResampling, + infer_channel_dimension_format, + is_scaled_image, + make_flat_list_of_images, + to_numpy_array, + valid_images, +) +from ...utils import TensorType, is_torch_available, logging, requires_backends + + +if is_torch_available(): + import torch + + +logger = logging.get_logger(__name__) + + +# See https://huggingface.co/papers/2212.02499 at 3.1 Redefining Output Spaces as "Images" - Semantic Segmentation from PAINTER paper +# Taken from https://github.com/Abdullah-Meda/Painter/blob/main/Painter/data/coco_semseg/gen_color_coco_panoptic_segm.py#L31 +def build_palette(num_labels: int) -> list[tuple[int, int]]: + base = int(num_labels ** (1 / 3)) + 1 + margin = 256 // base + + # we assume that class_idx 0 is the background which is mapped to black + color_list = [(0, 0, 0)] + for location in range(num_labels): + num_seq_r = location // base**2 + num_seq_g = (location % base**2) // base + num_seq_b = location % base + + R = 255 - num_seq_r * margin + G = 255 - num_seq_g * margin + B = 255 - num_seq_b * margin + + color_list.append((R, G, B)) + + return color_list + + +def mask_to_rgb( + mask: np.ndarray, palette: list[tuple[int, int]] | None = None, data_format: ChannelDimension | None = None +) -> np.ndarray: + data_format = data_format if data_format is not None else ChannelDimension.FIRST + + if palette is not None: + height, width = mask.shape + + rgb_mask = np.zeros((3, height, width), dtype=np.uint8) + + classes_in_mask = np.unique(mask) + + for class_idx in classes_in_mask: + rgb_value = palette[class_idx] + class_mask = (mask == class_idx).astype(np.uint8) + class_mask = np.expand_dims(class_mask, axis=-1) + class_rgb_mask = class_mask * np.array(rgb_value) + class_rgb_mask = np.moveaxis(class_rgb_mask, -1, 0) + rgb_mask += class_rgb_mask.astype(np.uint8) + + rgb_mask = np.clip(rgb_mask, 0, 255).astype(np.uint8) + + else: + rgb_mask = np.repeat(mask[None, ...], 3, axis=0) + + return to_channel_dimension_format(rgb_mask, data_format) + + +class SegGptImageProcessor(BaseImageProcessor): + r""" + Constructs a SegGpt image processor. + + Args: + do_resize (`bool`, *optional*, defaults to `True`): + Whether to resize the image's (height, width) dimensions to the specified `(size["height"], + size["width"])`. Can be overridden by the `do_resize` parameter in the `preprocess` method. + size (`dict`, *optional*, defaults to `{"height": 448, "width": 448}`): + Size of the output image after resizing. Can be overridden by the `size` parameter in the `preprocess` + method. + resample (`PILImageResampling`, *optional*, defaults to `Resampling.BICUBIC`): + Resampling filter to use if resizing the image. Can be overridden by the `resample` parameter in the + `preprocess` method. + do_rescale (`bool`, *optional*, defaults to `True`): + Whether to rescale the image by the specified scale `rescale_factor`. Can be overridden by the `do_rescale` + parameter in the `preprocess` method. + rescale_factor (`int` or `float`, *optional*, defaults to `1/255`): + Scale factor to use if rescaling the image. Can be overridden by the `rescale_factor` parameter in the + `preprocess` method. + do_normalize (`bool`, *optional*, defaults to `True`): + Whether to normalize the image. Can be overridden by the `do_normalize` parameter in the `preprocess` + method. + image_mean (`float` or `list[float]`, *optional*, defaults to `IMAGENET_DEFAULT_MEAN`): + Mean to use if normalizing the image. This is a float or list of floats the length of the number of + channels in the image. Can be overridden by the `image_mean` parameter in the `preprocess` method. + image_std (`float` or `list[float]`, *optional*, defaults to `IMAGENET_DEFAULT_STD`): + Standard deviation to use if normalizing the image. This is a float or list of floats the length of the + number of channels in the image. Can be overridden by the `image_std` parameter in the `preprocess` method. + do_convert_rgb (`bool`, *optional*, defaults to `True`): + Whether to convert the prompt mask to RGB format. Can be overridden by the `do_convert_rgb` parameter in the + `preprocess` method. + """ + + model_input_names = ["pixel_values"] + + def __init__( + self, + do_resize: bool = True, + size: dict[str, int] | None = None, + resample: PILImageResampling = PILImageResampling.BICUBIC, + do_rescale: bool = True, + rescale_factor: int | float = 1 / 255, + do_normalize: bool = True, + image_mean: float | list[float] | None = None, + image_std: float | list[float] | None = None, + do_convert_rgb: bool = True, + **kwargs, + ) -> None: + super().__init__(**kwargs) + size = size if size is not None else {"height": 448, "width": 448} + size = get_size_dict(size) + self.do_resize = do_resize + self.do_rescale = do_rescale + self.do_normalize = do_normalize + self.size = size + self.resample = resample + self.rescale_factor = rescale_factor + self.image_mean = image_mean if image_mean is not None else IMAGENET_DEFAULT_MEAN + self.image_std = image_std if image_std is not None else IMAGENET_DEFAULT_STD + self.do_convert_rgb = do_convert_rgb + + def get_palette(self, num_labels: int) -> list[tuple[int, int]]: + """Build a palette to map the prompt mask from a single channel to a 3 channel RGB. + + Args: + num_labels (`int`): + Number of classes in the segmentation task (excluding the background). + + Returns: + `list[tuple[int, int]]`: Palette to map the prompt mask from a single channel to a 3 channel RGB. + """ + return build_palette(num_labels) + + def mask_to_rgb( + self, + image: np.ndarray, + palette: list[tuple[int, int]] | None = None, + data_format: str | ChannelDimension | None = None, + ) -> np.ndarray: + """Converts a segmentation map to RGB format. + + Args: + image (`np.ndarray`): + Segmentation map with dimensions (height, width) where pixel values represent the class index. + palette (`list[tuple[int, int]]`, *optional*, defaults to `None`): + Palette to use to convert the mask to RGB format. If unset, the mask is duplicated across the channel + dimension. + data_format (`ChannelDimension` or `str`, *optional*): + The channel dimension format for the output image. If unset, the channel dimension format of the input + image is used. Can be one of: + - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format. + - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format. + + Returns: + `np.ndarray`: The mask in RGB format. + """ + return mask_to_rgb(image, palette=palette, data_format=data_format) + + # Copied from transformers.models.vit.image_processing_vit.ViTImageProcessor.resize with PILImageResampling.BILINEAR->PILImageResampling.BICUBIC + def resize( + self, + image: np.ndarray, + size: dict[str, int], + resample: PILImageResampling = PILImageResampling.BICUBIC, + data_format: str | ChannelDimension | None = None, + input_data_format: str | ChannelDimension | None = None, + **kwargs, + ) -> np.ndarray: + """ + Resize an image to `(size["height"], size["width"])`. + + Args: + image (`np.ndarray`): + Image to resize. + size (`dict[str, int]`): + Dictionary in the format `{"height": int, "width": int}` specifying the size of the output image. + resample (`PILImageResampling`, *optional*, defaults to `PILImageResampling.BICUBIC`): + `PILImageResampling` filter to use when resizing the image e.g. `PILImageResampling.BICUBIC`. + data_format (`ChannelDimension` or `str`, *optional*): + The channel dimension format for the output image. If unset, the channel dimension format of the input + image is used. Can be one of: + - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format. + - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format. + - `"none"` or `ChannelDimension.NONE`: image in (height, width) format. + input_data_format (`ChannelDimension` or `str`, *optional*): + The channel dimension format for the input image. If unset, the channel dimension format is inferred + from the input image. Can be one of: + - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format. + - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format. + - `"none"` or `ChannelDimension.NONE`: image in (height, width) format. + + Returns: + `np.ndarray`: The resized image. + """ + size = get_size_dict(size) + if "height" not in size or "width" not in size: + raise ValueError(f"The `size` dictionary must contain the keys `height` and `width`. Got {size.keys()}") + output_size = (size["height"], size["width"]) + return resize( + image, + size=output_size, + resample=resample, + data_format=data_format, + input_data_format=input_data_format, + **kwargs, + ) + + def _preprocess_step( + self, + images: ImageInput, + do_resize: bool | None = None, + size: dict[str, int] | None = None, + resample: PILImageResampling | None = None, + do_rescale: bool | None = None, + rescale_factor: float | None = None, + do_normalize: bool | None = None, + image_mean: float | list[float] | None = None, + image_std: float | list[float] | None = None, + data_format: str | ChannelDimension = ChannelDimension.FIRST, + input_data_format: str | ChannelDimension | None = None, + do_convert_rgb: bool | None = None, + num_labels: int | None = None, + **kwargs, + ): + """ + Preprocess an image or batch of images. + + Args: + images (`ImageInput`): + Image to _preprocess. Expects a single or batch of images with pixel values ranging from 0 to 255. If + passing in images with pixel values between 0 and 1, set `do_rescale=False`. + do_resize (`bool`, *optional*, defaults to `self.do_resize`): + Whether to resize the image. + size (`dict[str, int]`, *optional*, defaults to `self.size`): + Dictionary in the format `{"height": h, "width": w}` specifying the size of the output image after + resizing. + resample (`PILImageResampling` filter, *optional*, defaults to `self.resample`): + `PILImageResampling` filter to use if resizing the image e.g. `PILImageResampling.BICUBIC`. Only has + an effect if `do_resize` is set to `True`. + do_rescale (`bool`, *optional*, defaults to `self.do_rescale`): + Whether to rescale the image values between [0 - 1]. + rescale_factor (`float`, *optional*, defaults to `self.rescale_factor`): + Rescale factor to rescale the image by if `do_rescale` is set to `True`. + do_normalize (`bool`, *optional*, defaults to `self.do_normalize`): + Whether to normalize the image. + image_mean (`float` or `list[float]`, *optional*, defaults to `self.image_mean`): + Image mean to use if `do_normalize` is set to `True`. + image_std (`float` or `list[float]`, *optional*, defaults to `self.image_std`): + Image standard deviation to use if `do_normalize` is set to `True`. + return_tensors (`str` or `TensorType`, *optional*): + The type of tensors to return. Can be one of: + - Unset: Return a list of `np.ndarray`. + - `TensorType.PYTORCH` or `'pt'`: Return a batch of type `torch.Tensor`. + - `TensorType.NUMPY` or `'np'`: Return a batch of type `np.ndarray`. + data_format (`ChannelDimension` or `str`, *optional*, defaults to `ChannelDimension.FIRST`): + The channel dimension format for the output image. Can be one of: + - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format. + - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format. + - Unset: Use the channel dimension format of the input image. + input_data_format (`ChannelDimension` or `str`, *optional*): + The channel dimension format for the input image. If unset, the channel dimension format is inferred + from the input image. Can be one of: + - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format. + - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format. + - `"none"` or `ChannelDimension.NONE`: image in (height, width) format. + do_convert_rgb (`bool`, *optional*, defaults to `self.do_convert_rgb`): + Whether to convert the prompt mask to RGB format. If `num_labels` is specified, a palette will be built + to map the prompt mask from a single channel to a 3 channel RGB. If unset, the prompt mask is duplicated + across the channel dimension. Must be set to `False` if the prompt mask is already in RGB format. + num_labels: (`int`, *optional*): + Number of classes in the segmentation task (excluding the background). If specified, a palette will be + built, assuming that class_idx 0 is the background, to map the prompt mask from a single class_idx + channel to a 3 channel RGB. Not specifying this will result in the prompt mask either being passed + through as is if it is already in RGB format or being duplicated across the channel dimension. + """ + do_resize = do_resize if do_resize is not None else self.do_resize + do_rescale = do_rescale if do_rescale is not None else self.do_rescale + do_normalize = do_normalize if do_normalize is not None else self.do_normalize + do_convert_rgb = do_convert_rgb if do_convert_rgb is not None else self.do_convert_rgb + resample = resample if resample is not None else self.resample + rescale_factor = rescale_factor if rescale_factor is not None else self.rescale_factor + image_mean = image_mean if image_mean is not None else self.image_mean + image_std = image_std if image_std is not None else self.image_std + + size = size if size is not None else self.size + size_dict = get_size_dict(size) + + # If segmentation map is passed we expect 2D images + images = make_flat_list_of_images(images, expected_ndims=2 if do_convert_rgb else 3) + + if not valid_images(images): + raise ValueError("Invalid image type. Must be of type PIL.Image.Image, numpy.ndarray, or torch.Tensor") + + if do_resize and size is None: + raise ValueError("Size must be specified if do_resize is True.") + + if do_rescale and rescale_factor is None: + raise ValueError("Rescale factor must be specified if do_rescale is True.") + + if do_normalize and (image_mean is None or image_std is None): + raise ValueError("Image mean and std must be specified if do_normalize is True.") + + # All transformations expect numpy arrays. + images = [to_numpy_array(image) for image in images] + + if do_rescale and is_scaled_image(images[0]): + logger.warning_once( + "It looks like you are trying to rescale already rescaled images. If the input" + " images have pixel values between 0 and 1, set `do_rescale=False` to avoid rescaling them again." + ) + + if input_data_format is None and not do_convert_rgb: + # We assume that all images have the same channel dimension format. + input_data_format = infer_channel_dimension_format(images[0]) + + if do_convert_rgb: + palette = self.get_palette(num_labels) if num_labels is not None else None + # Since this is the input for the next transformations its format should be the same as the input_data_format + images = [ + self.mask_to_rgb(image=image, palette=palette, data_format=ChannelDimension.FIRST) for image in images + ] + input_data_format = ChannelDimension.FIRST + + if do_resize: + images = [ + self.resize(image=image, size=size_dict, resample=resample, input_data_format=input_data_format) + for image in images + ] + + if do_rescale: + images = [ + self.rescale(image=image, scale=rescale_factor, input_data_format=input_data_format) + for image in images + ] + + if do_normalize: + images = [ + self.normalize(image=image, mean=image_mean, std=image_std, input_data_format=input_data_format) + for image in images + ] + + images = [ + to_channel_dimension_format(image, data_format, input_channel_dim=input_data_format) for image in images + ] + + return images + + def preprocess( + self, + images: ImageInput | None = None, + prompt_images: ImageInput | None = None, + prompt_masks: ImageInput | None = None, + do_resize: bool | None = None, + size: dict[str, int] | None = None, + resample: PILImageResampling | None = None, + do_rescale: bool | None = None, + rescale_factor: float | None = None, + do_normalize: bool | None = None, + image_mean: float | list[float] | None = None, + image_std: float | list[float] | None = None, + do_convert_rgb: bool | None = None, + num_labels: int | None = None, + return_tensors: str | TensorType | None = None, + data_format: str | ChannelDimension = ChannelDimension.FIRST, + input_data_format: str | ChannelDimension | None = None, + **kwargs, + ): + """ + Preprocess an image or batch of images. + + Args: + images (`ImageInput`): + Image to _preprocess. Expects a single or batch of images with pixel values ranging from 0 to 255. If + passing in images with pixel values between 0 and 1, set `do_rescale=False`. + prompt_images (`ImageInput`): + Prompt image to _preprocess. Expects a single or batch of images with pixel values ranging from 0 to 255. If + passing in images with pixel values between 0 and 1, set `do_rescale=False`. + prompt_masks (`ImageInput`): + Prompt mask from prompt image to _preprocess that specify prompt_masks value in the preprocessed output. + Can either be in the format of segmentation maps (no channels) or RGB images. If in the format of + RGB images, `do_convert_rgb` should be set to `False`. If in the format of segmentation maps, `num_labels` + specifying `num_labels` is recommended to build a palette to map the prompt mask from a single channel to + a 3 channel RGB. If `num_labels` is not specified, the prompt mask will be duplicated across the channel + dimension. + do_resize (`bool`, *optional*, defaults to `self.do_resize`): + Whether to resize the image. + size (`dict[str, int]`, *optional*, defaults to `self.size`): + Dictionary in the format `{"height": h, "width": w}` specifying the size of the output image after + resizing. + resample (`PILImageResampling` filter, *optional*, defaults to `self.resample`): + `PILImageResampling` filter to use if resizing the image e.g. `PILImageResampling.BICUBIC`. Only has + an effect if `do_resize` is set to `True`. Doesn't apply to prompt mask as it is resized using nearest. + do_rescale (`bool`, *optional*, defaults to `self.do_rescale`): + Whether to rescale the image values between [0 - 1]. + rescale_factor (`float`, *optional*, defaults to `self.rescale_factor`): + Rescale factor to rescale the image by if `do_rescale` is set to `True`. + do_normalize (`bool`, *optional*, defaults to `self.do_normalize`): + Whether to normalize the image. + image_mean (`float` or `list[float]`, *optional*, defaults to `self.image_mean`): + Image mean to use if `do_normalize` is set to `True`. + image_std (`float` or `list[float]`, *optional*, defaults to `self.image_std`): + Image standard deviation to use if `do_normalize` is set to `True`. + do_convert_rgb (`bool`, *optional*, defaults to `self.do_convert_rgb`): + Whether to convert the prompt mask to RGB format. If `num_labels` is specified, a palette will be built + to map the prompt mask from a single channel to a 3 channel RGB. If unset, the prompt mask is duplicated + across the channel dimension. Must be set to `False` if the prompt mask is already in RGB format. + num_labels: (`int`, *optional*): + Number of classes in the segmentation task (excluding the background). If specified, a palette will be + built, assuming that class_idx 0 is the background, to map the prompt mask from a plain segmentation map + with no channels to a 3 channel RGB. Not specifying this will result in the prompt mask either being passed + through as is if it is already in RGB format (if `do_convert_rgb` is false) or being duplicated + across the channel dimension. + return_tensors (`str` or `TensorType`, *optional*): + The type of tensors to return. Can be one of: + - Unset: Return a list of `np.ndarray`. + - `TensorType.PYTORCH` or `'pt'`: Return a batch of type `torch.Tensor`. + - `TensorType.NUMPY` or `'np'`: Return a batch of type `np.ndarray`. + data_format (`ChannelDimension` or `str`, *optional*, defaults to `ChannelDimension.FIRST`): + The channel dimension format for the output image. Can be one of: + - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format. + - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format. + - Unset: Use the channel dimension format of the input image. + input_data_format (`ChannelDimension` or `str`, *optional*): + The channel dimension format for the input image. If unset, the channel dimension format is inferred + from the input image. Can be one of: + - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format. + - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format. + - `"none"` or `ChannelDimension.NONE`: image in (height, width) format. + """ + if all(v is None for v in [images, prompt_images, prompt_masks]): + raise ValueError("At least one of images, prompt_images, prompt_masks must be specified.") + + data = {} + + if images is not None: + images = self._preprocess_step( + images, + is_mask=False, + do_resize=do_resize, + size=size, + resample=resample, + do_rescale=do_rescale, + rescale_factor=rescale_factor, + do_normalize=do_normalize, + image_mean=image_mean, + image_std=image_std, + do_convert_rgb=False, + data_format=data_format, + input_data_format=input_data_format, + **kwargs, + ) + + data["pixel_values"] = images + + if prompt_images is not None: + prompt_images = self._preprocess_step( + prompt_images, + is_mask=False, + do_resize=do_resize, + size=size, + resample=resample, + do_rescale=do_rescale, + rescale_factor=rescale_factor, + do_normalize=do_normalize, + image_mean=image_mean, + image_std=image_std, + do_convert_rgb=False, + data_format=data_format, + input_data_format=input_data_format, + **kwargs, + ) + + data["prompt_pixel_values"] = prompt_images + + if prompt_masks is not None: + prompt_masks = self._preprocess_step( + prompt_masks, + do_resize=do_resize, + size=size, + resample=PILImageResampling.NEAREST, + do_rescale=do_rescale, + rescale_factor=rescale_factor, + do_normalize=do_normalize, + image_mean=image_mean, + image_std=image_std, + do_convert_rgb=do_convert_rgb, + num_labels=num_labels, + data_format=data_format, + input_data_format=input_data_format, + **kwargs, + ) + + data["prompt_masks"] = prompt_masks + + return BatchFeature(data=data, tensor_type=return_tensors) + + def post_process_semantic_segmentation( + self, outputs, target_sizes: list[tuple[int, int]] | None = None, num_labels: int | None = None + ): + """ + Converts the output of [`SegGptImageSegmentationOutput`] into segmentation maps. Only supports + PyTorch. + + Args: + outputs ([`SegGptImageSegmentationOutput`]): + Raw outputs of the model. + target_sizes (`list[tuple[int, int]]`, *optional*): + List of length (batch_size), where each list item (`tuple[int, int]`) corresponds to the requested + final size (height, width) of each prediction. If left to None, predictions will not be resized. + num_labels (`int`, *optional*): + Number of classes in the segmentation task (excluding the background). If specified, a palette will be + built, assuming that class_idx 0 is the background, to map prediction masks from RGB values to class + indices. This value should be the same used when preprocessing inputs. + Returns: + semantic_segmentation: `list[torch.Tensor]` of length `batch_size`, where each item is a semantic + segmentation map of shape (height, width) corresponding to the target_sizes entry (if `target_sizes` is + specified). Each entry of each `torch.Tensor` correspond to a semantic class id. + """ + requires_backends(self, ["torch"]) + # batch_size x num_channels x 2*height x width + masks = outputs.pred_masks + + # Predicted mask and prompt are concatenated in the height dimension + # batch_size x num_channels x height x width + masks = masks[:, :, masks.shape[2] // 2 :, :] + + # To unnormalize we need to permute to channel last + # batch_size x height x width x num_channels + std = torch.tensor(self.image_std).to(masks.device) + mean = torch.tensor(self.image_mean).to(masks.device) + + masks = masks.permute(0, 2, 3, 1) * std + mean + + # batch_size x num_channels x height x width + masks = masks.permute(0, 3, 1, 2) + + # Clip to match with palette if specified + masks = torch.clip(masks * 255, 0, 255) + + semantic_segmentation = [] + palette_tensor = None + palette = self.get_palette(num_labels) if num_labels is not None else None + if palette is not None: + palette_tensor = torch.tensor(palette).to(device=masks.device, dtype=torch.float) + _, num_channels, _, _ = masks.shape + palette_tensor = palette_tensor.view(1, 1, num_labels + 1, num_channels) + + for idx, mask in enumerate(masks): + if target_sizes is not None: + mask = torch.nn.functional.interpolate( + mask.unsqueeze(0), + size=target_sizes[idx], + mode="nearest", + )[0] + + if num_labels is not None: + channels, height, width = mask.shape + dist = mask.permute(1, 2, 0).view(height, width, 1, channels) + dist = dist - palette_tensor + dist = torch.pow(dist, 2) + dist = torch.sum(dist, dim=-1) + pred = dist.argmin(dim=-1) + + else: + # If no palette is specified SegGpt will try to paint using the mask class idx as RGB + pred = mask.mean(dim=0).int() + + semantic_segmentation.append(pred) + + return semantic_segmentation + + +__all__ = ["SegGptImageProcessor"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/seggpt/modeling_seggpt.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/seggpt/modeling_seggpt.py new file mode 100644 index 0000000000000000000000000000000000000000..c51383da8b6356ee11373a2c5bf64a7af4960861 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/seggpt/modeling_seggpt.py @@ -0,0 +1,962 @@ +# Copyright 2024 The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""PyTorch SegGpt model.""" + +import collections.abc +from dataclasses import dataclass + +import torch +from torch import nn +from torch.nn import functional as F + +from ... import initialization as init +from ...activations import ACT2FN +from ...modeling_layers import GradientCheckpointingLayer +from ...modeling_utils import PreTrainedModel +from ...utils import ModelOutput, auto_docstring, logging, torch_int +from .configuration_seggpt import SegGptConfig + + +logger = logging.get_logger(__name__) + + +@dataclass +@auto_docstring( + custom_intro=""" + Output type of [`SegGptEncoderOutput`]. + """ +) +class SegGptEncoderOutput(ModelOutput): + r""" + last_hidden_state (`torch.FloatTensor` of shape `(batch_size, patch_height, patch_width, hidden_size)`): + Sequence of hidden-states at the output of the last layer of the model. + hidden_states (`tuple[torch.FloatTensor]`, `optional`, returned when `config.output_hidden_states=True`): + Tuple of `torch.FloatTensor` (one for the output of the embeddings + one for the output of each layer) + of shape `(batch_size, patch_height, patch_width, hidden_size)`. + attentions (`tuple[torch.FloatTensor]`, `optional`, returned when `config.output_attentions=True`): + Tuple of *torch.FloatTensor* (one for each layer) of shape + `(batch_size, num_heads, seq_len, seq_len)`. + intermediate_hidden_states (`tuple[torch.FloatTensor]`, *optional*, returned when `config.intermediate_hidden_state_indices` is set): + Tuple of `torch.FloatTensor` of shape `(batch_size, patch_height, patch_width, hidden_size)`. + Each element in the Tuple corresponds to the output of the layer specified in `config.intermediate_hidden_state_indices`. + Additionally, each feature passes through a LayerNorm. + """ + + last_hidden_state: torch.FloatTensor + hidden_states: tuple[torch.FloatTensor] | None = None + attentions: tuple[torch.FloatTensor] | None = None + intermediate_hidden_states: tuple[torch.FloatTensor] | None = None + + +@dataclass +@auto_docstring( + custom_intro=""" + Output type of [`SegGptImageSegmentationOutput`]. + """ +) +class SegGptImageSegmentationOutput(ModelOutput): + r""" + loss (`torch.FloatTensor`, *optional*, returned when `labels` is provided): + The loss value. + pred_masks (`torch.FloatTensor` of shape `(batch_size, num_channels, height, width)`): + The predicted masks. + hidden_states (`tuple[torch.FloatTensor]`, `optional`, returned when `config.output_hidden_states=True`): + Tuple of `torch.FloatTensor` (one for the output of the embeddings + one for the output of each layer) + of shape `(batch_size, patch_height, patch_width, hidden_size)`. + attentions (`tuple[torch.FloatTensor]`, `optional`, returned when `config.output_attentions=True`): + Tuple of `torch.FloatTensor` (one for each layer) of shape + `(batch_size, num_heads, seq_len, seq_len)`. + """ + + loss: torch.FloatTensor | None = None + pred_masks: torch.FloatTensor | None = None + hidden_states: tuple[torch.FloatTensor] | None = None + attentions: tuple[torch.FloatTensor] | None = None + + +# Copied from transformers.models.sam.modeling_sam.SamPatchEmbeddings with Sam->SegGpt +class SegGptPatchEmbeddings(nn.Module): + """ + This class turns `pixel_values` of shape `(batch_size, num_channels, height, width)` into the initial + `hidden_states` (patch embeddings) of shape `(batch_size, seq_length, hidden_size)` to be consumed by a + Transformer. + """ + + def __init__(self, config): + super().__init__() + image_size, patch_size = config.image_size, config.patch_size + num_channels, hidden_size = config.num_channels, config.hidden_size + image_size = image_size if isinstance(image_size, collections.abc.Iterable) else (image_size, image_size) + patch_size = patch_size if isinstance(patch_size, collections.abc.Iterable) else (patch_size, patch_size) + num_patches = (image_size[1] // patch_size[1]) * (image_size[0] // patch_size[0]) + self.image_size = image_size + self.patch_size = patch_size + self.num_channels = num_channels + self.num_patches = num_patches + + self.projection = nn.Conv2d(num_channels, hidden_size, kernel_size=patch_size, stride=patch_size) + + def forward(self, pixel_values): + batch_size, num_channels, height, width = pixel_values.shape + if num_channels != self.num_channels: + raise ValueError( + "Make sure that the channel dimension of the pixel values match with the one set in the configuration." + ) + if height != self.image_size[0] or width != self.image_size[1]: + raise ValueError( + f"Input image size ({height}*{width}) doesn't match model ({self.image_size[0]}*{self.image_size[1]})." + ) + embeddings = self.projection(pixel_values).permute(0, 2, 3, 1) + return embeddings + + +class SegGptEmbeddings(nn.Module): + """ + Construct the embeddings from patch, position embeddings for input and prompt. + """ + + def __init__(self, config: SegGptConfig) -> None: + super().__init__() + + self.mask_token = nn.Parameter(torch.zeros(1, 1, 1, config.hidden_size)) + self.segment_token_input = nn.Parameter(torch.zeros(1, 1, 1, config.hidden_size)) + self.segment_token_prompt = nn.Parameter(torch.zeros(1, 1, 1, config.hidden_size)) + # token for seg types + self.type_token_semantic = nn.Parameter(torch.zeros(1, 1, 1, config.hidden_size)) + self.type_token_instance = nn.Parameter(torch.zeros(1, 1, 1, config.hidden_size)) + + self.patch_embeddings = SegGptPatchEmbeddings(config) + + num_positions = (config.pretrain_image_size // config.patch_size) ** 2 + 1 + self.position_embeddings = nn.Parameter(torch.randn(1, num_positions, config.hidden_size)) + self.dropout = nn.Dropout(config.hidden_dropout_prob) + + def interpolate_pos_encoding(self, height: int, width: int) -> torch.Tensor: + patch_pos_embed = self.position_embeddings[:, 1:] + num_patches = patch_pos_embed.shape[1] + pretrain_patch_size = torch_int(num_patches**0.5) + + # always interpolate when tracing to ensure the exported model works for dynamic input shapes + if torch.jit.is_tracing() or pretrain_patch_size != height or pretrain_patch_size != width: + patch_pos_embed = F.interpolate( + patch_pos_embed.reshape(1, pretrain_patch_size, pretrain_patch_size, -1).permute(0, 3, 1, 2), + size=(height, width), + mode="bicubic", + align_corners=False, + ) + + return patch_pos_embed.permute(0, 2, 3, 1) + else: + return patch_pos_embed.reshape(1, height, width, -1) + + def forward( + self, + pixel_values: torch.Tensor, + prompt_pixel_values: torch.Tensor, + bool_masked_pos: torch.BoolTensor | None = None, + embedding_type: str | None = None, + ) -> torch.Tensor: + input_embeddings = self.patch_embeddings(pixel_values) + prompt_embeddings = self.patch_embeddings(prompt_pixel_values) + + batch_size, patch_height, patch_width, _ = input_embeddings.shape + + mask_token = self.mask_token.expand(batch_size, patch_height, patch_width, -1) + # replace the masked visual tokens by mask_token + w = bool_masked_pos.unsqueeze(-1).type_as(mask_token).reshape(-1, patch_height, patch_width, 1) + prompt_embeddings = prompt_embeddings * (1 - w) + mask_token * w + + embedding_type = embedding_type if embedding_type is not None else "instance" + + # add positional encoding to each token + pos_embed = self.interpolate_pos_encoding(patch_height, patch_width) + + # add segment token + input_embeddings = input_embeddings + self.segment_token_input + prompt_embeddings = prompt_embeddings + self.segment_token_prompt + + # add position embedding skipping CLS + input_embeddings = input_embeddings + pos_embed + prompt_embeddings = prompt_embeddings + pos_embed + + # add type embedding to each token + if embedding_type == "semantic": + type_embedding = self.type_token_semantic + elif embedding_type == "instance": + type_embedding = self.type_token_instance + else: + raise ValueError(f"Embedding type should be either 'semantic' or 'instance', but got {embedding_type}") + + input_embeddings = input_embeddings + type_embedding + prompt_embeddings = prompt_embeddings + type_embedding + + embeddings = torch.cat((input_embeddings, prompt_embeddings), dim=0) + + return embeddings + + +class SegGptAttention(nn.Module): + """Multi-head Attention block with relative position embeddings.""" + + def __init__(self, config): + super().__init__() + image_size, patch_size = config.image_size, config.patch_size + image_size = image_size if isinstance(image_size, collections.abc.Iterable) else (image_size, image_size) + patch_size = patch_size if isinstance(patch_size, collections.abc.Iterable) else (patch_size, patch_size) + + input_size = (image_size[0] // config.patch_size, image_size[1] // config.patch_size) + head_dim = config.hidden_size // config.num_attention_heads + + self.num_attention_heads = config.num_attention_heads + self.scale = head_dim**-0.5 + + self.qkv = nn.Linear(config.hidden_size, config.hidden_size * 3, bias=config.qkv_bias) + self.proj = nn.Linear(config.hidden_size, config.hidden_size) + + self.use_relative_position_embeddings = config.use_relative_position_embeddings + if self.use_relative_position_embeddings: + if input_size is None: + raise ValueError("Input size must be provided if using relative positional encoding.") + + # initialize relative positional embeddings + self.rel_pos_h = nn.Parameter(torch.zeros(2 * input_size[0] - 1, head_dim)) + self.rel_pos_w = nn.Parameter(torch.zeros(2 * input_size[1] - 1, head_dim)) + + def get_rel_pos(self, q_size: int, k_size: int, rel_pos: torch.Tensor) -> torch.Tensor: + """ + Get relative positional embeddings according to the relative positions of + query and key sizes. + + Args: + q_size (int): + size of the query. + k_size (int): + size of key k. + rel_pos (`torch.Tensor`): + relative position embeddings (L, channel). + + Returns: + Extracted positional embeddings according to relative positions. + """ + max_rel_dist = int(2 * max(q_size, k_size) - 1) + # Interpolate rel pos. + rel_pos_resized = F.interpolate( + rel_pos.reshape(1, rel_pos.shape[0], -1).permute(0, 2, 1), + size=max_rel_dist, + mode="linear", + ) + rel_pos_resized = rel_pos_resized.reshape(-1, max_rel_dist).permute(1, 0) + + # Scale the coords with short length if shapes for q and k are different. + q_coords = torch.arange(q_size)[:, None] * max(k_size / q_size, 1.0) + k_coords = torch.arange(k_size)[None, :] * max(q_size / k_size, 1.0) + relative_coords = (q_coords - k_coords) + (k_size - 1) * max(q_size / k_size, 1.0) + + return rel_pos_resized[relative_coords.long()] + + def add_decomposed_rel_pos( + self, + attn: torch.Tensor, + query: torch.Tensor, + rel_pos_h: torch.Tensor, + rel_pos_w: torch.Tensor, + q_size: tuple[int, int], + k_size: tuple[int, int], + ) -> torch.Tensor: + """ + Calculate decomposed Relative Positional Embeddings from :paper:`mvitv2`. + https://github.com/facebookresearch/mvit/blob/19786631e330df9f3622e5402b4a419a263a2c80/mvit/models/attention.py + + Args: + attn (`torch.Tensor`): + attention map. + query (`torch.Tensor`): + query q in the attention layer with shape (batch_size, query_height * query_width, channel). + rel_pos_h (`torch.Tensor`): + relative position embeddings (Lh, channel) for height axis. + rel_pos_w (`torch.Tensor`): + relative position embeddings (Lw, channel) for width axis. + q_size (tuple): + spatial sequence size of query q with (query_height, query_width). + k_size (tuple): + spatial sequence size of key k with (key_height, key_width). + + Returns: + attn (`torch.Tensor`): + attention map with added relative positional embeddings. + """ + query_height, query_width = q_size + key_height, key_width = k_size + relative_position_height = self.get_rel_pos(query_height, key_height, rel_pos_h) + relative_position_width = self.get_rel_pos(query_width, key_width, rel_pos_w) + + batch_size, _, dim = query.shape + reshaped_query = query.reshape(batch_size, query_height, query_width, dim) + rel_h = torch.einsum("bhwc,hkc->bhwk", reshaped_query, relative_position_height) + rel_w = torch.einsum("bhwc,wkc->bhwk", reshaped_query, relative_position_width) + attn = attn.reshape(batch_size, query_height, query_width, key_height, key_width) + attn = attn + rel_h[:, :, :, :, None] + rel_w[:, :, :, None, :] + attn = attn.reshape(batch_size, query_height * query_width, key_height * key_width) + return attn + + def forward(self, hidden_states: torch.Tensor, output_attentions=False) -> torch.Tensor: + batch_size, height, width, _ = hidden_states.shape + # qkv with shape (3, batch_size, nHead, height * width, channel) + qkv = ( + self.qkv(hidden_states) + .reshape(batch_size, height * width, 3, self.num_attention_heads, -1) + .permute(2, 0, 3, 1, 4) + ) + # q, k, v with shape (batch_size * nHead, height * width, channel) + query, key, value = qkv.reshape(3, batch_size * self.num_attention_heads, height * width, -1).unbind(0) + + attn_weights = (query * self.scale) @ key.transpose(-2, -1) + + if self.use_relative_position_embeddings: + attn_weights = self.add_decomposed_rel_pos( + attn_weights, query, self.rel_pos_h, self.rel_pos_w, (height, width), (height, width) + ) + + attn_weights = torch.nn.functional.softmax(attn_weights, dtype=torch.float32, dim=-1).to(query.dtype) + + if output_attentions: + # this operation is a bit awkward, but it's required to + # make sure that attn_weights keeps its gradient. + # In order to do so, attn_weights have to reshaped + # twice and have to be reused in the following + attn_weights_reshaped = attn_weights.view(batch_size, self.num_attention_heads, height * width, -1) + attn_weights = attn_weights_reshaped.view(batch_size * self.num_attention_heads, height * width, -1) + else: + attn_weights_reshaped = None + + attn_output = (attn_weights @ value).reshape(batch_size, self.num_attention_heads, height, width, -1) + attn_output = attn_output.permute(0, 2, 3, 1, 4).reshape(batch_size, height, width, -1) + + attn_output = self.proj(attn_output) + + return (attn_output, attn_weights_reshaped) + + +# Copied from transformers.models.sam.modeling_sam.SamMLPBlock with SamMLPBlock->SegGptMlp +class SegGptMlp(nn.Module): + def __init__(self, config): + super().__init__() + self.lin1 = nn.Linear(config.hidden_size, config.mlp_dim) + self.lin2 = nn.Linear(config.mlp_dim, config.hidden_size) + self.act = ACT2FN[config.hidden_act] + + def forward(self, hidden_states: torch.Tensor) -> torch.Tensor: + hidden_states = self.lin1(hidden_states) + hidden_states = self.act(hidden_states) + hidden_states = self.lin2(hidden_states) + return hidden_states + + +# Copied from transformers.models.beit.modeling_beit.drop_path +def drop_path(input: torch.Tensor, drop_prob: float = 0.0, training: bool = False) -> torch.Tensor: + """ + Drop paths (Stochastic Depth) per sample (when applied in main path of residual blocks). + + """ + if drop_prob == 0.0 or not training: + return input + keep_prob = 1 - drop_prob + shape = (input.shape[0],) + (1,) * (input.ndim - 1) # work with diff dim tensors, not just 2D ConvNets + random_tensor = keep_prob + torch.rand(shape, dtype=input.dtype, device=input.device) + random_tensor.floor_() # binarize + output = input.div(keep_prob) * random_tensor + return output + + +# Copied from transformers.models.beit.modeling_beit.BeitDropPath with Beit->SegGpt +class SegGptDropPath(nn.Module): + """Drop paths (Stochastic Depth) per sample (when applied in main path of residual blocks).""" + + def __init__(self, drop_prob: float | None = None) -> None: + super().__init__() + self.drop_prob = drop_prob + + def forward(self, hidden_states: torch.Tensor) -> torch.Tensor: + return drop_path(hidden_states, self.drop_prob, self.training) + + def extra_repr(self) -> str: + return f"p={self.drop_prob}" + + +class SegGptLayer(GradientCheckpointingLayer): + def __init__(self, config: SegGptConfig, drop_path_rate: float) -> None: + super().__init__() + self.attention = SegGptAttention(config) + self.mlp = SegGptMlp(config) + self.drop_path = SegGptDropPath(drop_path_rate) if drop_path_rate > 0.0 else nn.Identity() + self.layernorm_before = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps) + self.layernorm_after = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps) + + def forward( + self, + hidden_states: torch.Tensor, + ensemble_cond: int, + feature_ensemble: bool = False, + output_attentions: bool = False, + ) -> tuple[torch.Tensor, torch.Tensor] | tuple[torch.Tensor]: + self_attention_outputs = self.attention( + self.layernorm_before(hidden_states), # in SegGpt, layernorm is applied before self-attention + output_attentions=output_attentions, + ) + attention_output = self_attention_outputs[0] + outputs = self_attention_outputs[1:] # add self attentions if we output attention weights + + if feature_ensemble and attention_output.shape[0] // 2 >= ensemble_cond: + prompt, inputs = attention_output.split(attention_output.shape[1] // 2, dim=1) + if ensemble_cond == 2: + num_prompts = attention_output.shape[0] // 2 + inputs = inputs.reshape(2, num_prompts, -1) + inputs = inputs.mean(dim=1, keepdim=True).expand_as(inputs) + inputs = inputs.reshape(*prompt.shape) + else: + inputs = inputs.mean(dim=0, keepdim=True).expand_as(inputs) + attention_output = torch.cat([prompt, inputs], dim=1) + + # first residual connection + hidden_states = self.drop_path(attention_output) + hidden_states + residual = hidden_states + + hidden_states = self.layernorm_after(hidden_states) + hidden_states = self.mlp(hidden_states) + hidden_states = residual + self.drop_path(hidden_states) + + outputs = (hidden_states,) + outputs + + return outputs + + +class SegGptEncoder(nn.Module): + def __init__(self, config: SegGptConfig) -> None: + super().__init__() + self.config = config + dpr = [x.item() for x in torch.linspace(0, config.drop_path_rate, config.num_hidden_layers, device="cpu")] + self.layers = nn.ModuleList([SegGptLayer(config, dpr[i]) for i in range(config.num_hidden_layers)]) + self.layernorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps) + self.gradient_checkpointing = False + + def forward( + self, + hidden_states: torch.Tensor, + feature_ensemble: bool = False, + output_attentions: bool = False, + output_hidden_states: bool = False, + return_dict: bool = True, + ) -> tuple | SegGptEncoderOutput: + all_hidden_states = () if output_hidden_states else None + all_self_attentions = () if output_attentions else None + intermediate_hidden_states = [] + + for i, layer_module in enumerate(self.layers): + if output_hidden_states: + all_hidden_states = all_hidden_states + (hidden_states,) + + # Condition to check if we have the appropriate number of prompts to ensemble + ensemble_cond = 2 if self.config.merge_index > i else 1 + + layer_outputs = layer_module(hidden_states, ensemble_cond, feature_ensemble, output_attentions) + + hidden_states = layer_outputs[0] + + if i == self.config.merge_index: + hidden_states = ( + hidden_states[: hidden_states.shape[0] // 2] + hidden_states[hidden_states.shape[0] // 2 :] + ) * 0.5 + + if i in self.config.intermediate_hidden_state_indices: + intermediate_hidden_states.append(self.layernorm(hidden_states)) + + if output_attentions: + all_self_attentions = all_self_attentions + (layer_outputs[1],) + + if output_hidden_states: + all_hidden_states = all_hidden_states + (hidden_states,) + + if not return_dict: + return tuple( + v + for v in [hidden_states, all_hidden_states, all_self_attentions, intermediate_hidden_states] + if v is not None + ) + return SegGptEncoderOutput( + last_hidden_state=hidden_states, + hidden_states=all_hidden_states, + attentions=all_self_attentions, + intermediate_hidden_states=intermediate_hidden_states, + ) + + +# Copied from transformers.models.convnext.modeling_convnext.ConvNextLayerNorm with ConvNext->SegGpt +class SegGptLayerNorm(nn.LayerNorm): + r"""LayerNorm that supports two data formats: channels_last (default) or channels_first. + The ordering of the dimensions in the inputs. channels_last corresponds to inputs with shape (batch_size, height, + width, channels) while channels_first corresponds to inputs with shape (batch_size, channels, height, width). + """ + + def __init__(self, normalized_shape, *, eps=1e-6, data_format="channels_last", **kwargs): + super().__init__(normalized_shape, eps=eps, **kwargs) + if data_format not in ["channels_last", "channels_first"]: + raise NotImplementedError(f"Unsupported data format: {data_format}") + self.data_format = data_format + + def forward(self, features: torch.Tensor) -> torch.Tensor: + """ + Args: + features: Tensor of shape (batch_size, channels, height, width) OR (batch_size, height, width, channels) + """ + if self.data_format == "channels_first": + features = features.permute(0, 2, 3, 1) + features = super().forward(features) + features = features.permute(0, 3, 1, 2) + else: + features = super().forward(features) + return features + + +class SegGptDecoderHead(nn.Module): + def __init__(self, config): + super().__init__() + self.conv = nn.Conv2d( + config.decoder_hidden_size, + config.decoder_hidden_size, + kernel_size=3, + padding=1, + ) + self.layernorm = SegGptLayerNorm( + normalized_shape=config.decoder_hidden_size, eps=config.layer_norm_eps, data_format="channels_first" + ) + self.act_fct = ACT2FN[config.hidden_act] + self.head = nn.Conv2d(config.decoder_hidden_size, 3, kernel_size=1, bias=True) # decoder to patch + + def forward(self, hidden_states: torch.FloatTensor): + hidden_states = self.conv(hidden_states) + hidden_states = self.layernorm(hidden_states) + hidden_states = self.act_fct(hidden_states) + hidden_states = self.head(hidden_states) + + return hidden_states + + +class SegGptDecoder(nn.Module): + def __init__(self, config): + super().__init__() + self.decoder_embed = nn.Linear( + config.hidden_size * len(config.intermediate_hidden_state_indices), + config.patch_size**2 * config.decoder_hidden_size, + bias=True, + ) + self.decoder_pred = SegGptDecoderHead(config) + self.patch_size = config.patch_size + self.decoder_hidden_size = config.decoder_hidden_size + self.config = config + + def _reshape_hidden_states(self, hidden_states: torch.FloatTensor) -> torch.FloatTensor: + batch_size, patch_height, patch_width, _ = hidden_states.shape + hidden_states = hidden_states.reshape( + batch_size, patch_height, patch_width, self.patch_size, self.patch_size, self.decoder_hidden_size + ) + hidden_states = hidden_states.permute(0, 5, 1, 3, 2, 4) + hidden_states = hidden_states.reshape( + shape=(batch_size, -1, patch_height * self.patch_size, patch_width * self.patch_size) + ) + + return hidden_states + + def forward(self, hidden_states: torch.FloatTensor): + hidden_states = self.decoder_embed(hidden_states) + hidden_states = self._reshape_hidden_states(hidden_states) + hidden_states = self.decoder_pred(hidden_states) + + return hidden_states + + +@auto_docstring +class SegGptPreTrainedModel(PreTrainedModel): + config: SegGptConfig + base_model_prefix = "model" + main_input_name = "pixel_values" + input_modalities = ("image",) + supports_gradient_checkpointing = True + _no_split_modules = ["SegGptEmbeddings", "SegGptLayer"] + + @torch.no_grad() + def _init_weights(self, module: nn.Module) -> None: + """Initialize the weights""" + std = self.config.initializer_range + if isinstance(module, (nn.Linear, nn.Conv2d)): + init.trunc_normal_(module.weight, mean=0.0, std=std) + if module.bias is not None: + init.zeros_(module.bias) + elif isinstance(module, (nn.LayerNorm, SegGptLayerNorm)): + init.zeros_(module.bias) + init.ones_(module.weight) + elif isinstance(module, SegGptAttention): + init.trunc_normal_(module.rel_pos_h, mean=0.0, std=std) + init.trunc_normal_(module.rel_pos_w, mean=0.0, std=std) + elif isinstance(module, SegGptEmbeddings): + init.trunc_normal_(module.position_embeddings, mean=0.0, std=std) + init.normal_(module.mask_token, std=std) + init.normal_(module.segment_token_input, std=std) + init.normal_(module.segment_token_prompt, std=std) + init.normal_(module.type_token_semantic, std=std) + init.normal_(module.type_token_instance, std=std) + + +@auto_docstring +class SegGptModel(SegGptPreTrainedModel): + def __init__(self, config: SegGptConfig): + super().__init__(config) + self.config = config + + self.embeddings = SegGptEmbeddings(config) + self.encoder = SegGptEncoder(config) + + # Initialize weights and apply final processing + self.post_init() + + def get_input_embeddings(self) -> SegGptPatchEmbeddings: + return self.embeddings.patch_embeddings + + @auto_docstring + def forward( + self, + pixel_values: torch.Tensor, + prompt_pixel_values: torch.Tensor, + prompt_masks: torch.Tensor, + bool_masked_pos: torch.BoolTensor | None = None, + feature_ensemble: bool | None = None, + embedding_type: str | None = None, + labels: torch.FloatTensor | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + **kwargs, + ) -> tuple | SegGptEncoderOutput: + r""" + prompt_pixel_values (`torch.FloatTensor` of shape `(batch_size, num_channels, height, width)`): + Prompt pixel values. Prompt pixel values can be obtained using [`AutoImageProcessor`]. See + [`SegGptImageProcessor.__call__`] for details. + prompt_masks (`torch.FloatTensor` of shape `(batch_size, num_channels, height, width)`): + Prompt mask. Prompt mask can be obtained using [`AutoImageProcessor`]. See [`SegGptImageProcessor.__call__`] for + details. + bool_masked_pos (`torch.BoolTensor` of shape `(batch_size, num_patches)`, *optional*): + Boolean masked positions. Indicates which patches are masked (1) and which aren't (0). + feature_ensemble (`bool`, *optional*): + Boolean indicating whether to use feature ensemble or not. If `True`, the model will use feature ensemble + if we have at least two prompts. If `False`, the model will not use feature ensemble. This argument should + be considered when doing few-shot inference on an input image i.e. more than one prompt for the same image. + embedding_type (`str`, *optional*): + Embedding type. Indicates whether the prompt is a semantic or instance embedding. Can be either + instance or semantic. + labels (`torch.FloatTensor` of shape `(batch_size, num_channels, height, width)`, `optional`): + Ground truth mask for input images. + + Examples: + + ```python + >>> from transformers import SegGptImageProcessor, SegGptModel + >>> from PIL import Image + >>> import httpx + >>> from io import BytesIO + + >>> image_input_url = "https://raw.githubusercontent.com/baaivision/Painter/main/SegGPT/SegGPT_inference/examples/hmbb_2.jpg" + >>> image_prompt_url = "https://raw.githubusercontent.com/baaivision/Painter/main/SegGPT/SegGPT_inference/examples/hmbb_1.jpg" + >>> mask_prompt_url = "https://raw.githubusercontent.com/baaivision/Painter/main/SegGPT/SegGPT_inference/examples/hmbb_1_target.png" + + >>> with httpx.stream("GET", image_input_url) as response: + ... image_input = Image.open(BytesIO(response.read())) + + >>> with httpx.stream("GET", image_prompt_url) as response: + ... image_prompt = Image.open(BytesIO(response.read())) + + >>> with httpx.stream("GET", mask_prompt_url) as response: + ... mask_prompt = Image.open(BytesIO(response.read())).convert("L") + + >>> checkpoint = "BAAI/seggpt-vit-large" + >>> model = SegGptModel.from_pretrained(checkpoint) + >>> image_processor = SegGptImageProcessor.from_pretrained(checkpoint) + + >>> inputs = image_processor(images=image_input, prompt_images=image_prompt, prompt_masks=mask_prompt, return_tensors="pt") + + >>> outputs = model(**inputs) + >>> list(outputs.last_hidden_state.shape) + [1, 56, 28, 1024] + ``` + """ + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + feature_ensemble = feature_ensemble if feature_ensemble is not None else False + + expected_dtype = self.embeddings.patch_embeddings.projection.weight.dtype + pixel_values = pixel_values.to(expected_dtype) + prompt_pixel_values = prompt_pixel_values.to(expected_dtype) + + # Prepare inputs + pixel_values = torch.cat((prompt_pixel_values, pixel_values), dim=2) + prompt_pixel_values = ( + torch.cat((prompt_masks, prompt_masks), dim=2) + if labels is None + else torch.cat((prompt_masks, labels), dim=2) + ) + + if bool_masked_pos is None and labels is not None: + logger.warning_once( + "Labels were provided, but bool_masked_pos were not. It will be set to default value. If you're training the model, make sure to provide a bool_masked_pos." + ) + + # We concat on height axis so SegGPT can handle as a single image, hence we need to mask the portion + # of the mask prompt pixels that will be destinated to the prediction as they don't add any information. + # This is only the case for inference. In training, the model concat of prompt mask and label is masked + # and reconstructed together (In-Context Painting). + if bool_masked_pos is None: + num_patches = self.embeddings.patch_embeddings.num_patches + bool_masked_pos_zeros = torch.zeros(num_patches // 2, dtype=torch.bool, device=pixel_values.device) + bool_masked_pos_ones = torch.ones( + num_patches - num_patches // 2, dtype=torch.bool, device=pixel_values.device + ) + bool_masked_pos = torch.cat([bool_masked_pos_zeros, bool_masked_pos_ones]) + bool_masked_pos = bool_masked_pos.unsqueeze(0) + + embedding_output = self.embeddings( + pixel_values, prompt_pixel_values, embedding_type=embedding_type, bool_masked_pos=bool_masked_pos + ) + + encoder_outputs = self.encoder( + embedding_output, + feature_ensemble=feature_ensemble, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + + return encoder_outputs + + +def patchify(tensor: torch.Tensor, patch_size: int) -> torch.Tensor: + batch_size, num_channels, height, width = tensor.shape + patch_height = height // patch_size + patch_width = width // patch_size + + tensor = tensor.reshape(shape=(batch_size, num_channels, patch_height, patch_size, patch_width, patch_size)) + tensor = tensor.permute(0, 2, 4, 3, 5, 1) + tensor = tensor.reshape(shape=(batch_size, patch_height * patch_width, patch_size**2 * 3)) + + return tensor + + +def unpatchify(tensor: torch.Tensor, patch_height: int, patch_width: int) -> torch.Tensor: + batch_size = tensor.shape[0] + patch_size = int((tensor.shape[-1] / 3) ** 0.5) + if patch_height * patch_width != tensor.shape[1]: + raise ValueError( + f"Number of patches {tensor.shape[1]} does not match patch height ({patch_height}) and width ({patch_width})." + ) + + tensor = tensor.reshape(shape=(batch_size, patch_height, patch_width, patch_size, patch_size, 3)) + tensor = tensor.permute(0, 5, 1, 3, 2, 4) + tensor = tensor.reshape(shape=(batch_size, 3, patch_height * patch_size, patch_width * patch_size)) + + return tensor + + +class SegGptLoss(nn.Module): + def __init__(self, config): + super().__init__() + self.beta = config.beta + self.patch_size = config.patch_size + + def forward( + self, + prompt_masks: torch.FloatTensor, + pred_masks: torch.FloatTensor, + labels: torch.FloatTensor, + bool_masked_pos: torch.BoolTensor, + ): + """Computes the L1 loss between the predicted masks and the ground truth masks. + + Args: + prompt_masks (`torch.FloatTensor` of shape `(batch_size, num_channels, height, width)`): + Pixel values from mask prompt. + + pred_masks (`torch.FloatTensor` of shape `(batch_size, num_channels, 2*height, width)`): + Predicted masks. + + labels (`torch.FloatTensor` of shape `(batch_size, num_channels, height, width)`): + Ground truth mask for input images. + + bool_masked_pos (`torch.BoolTensor` of shape `(batch_size, num_patches)`): + Boolean masked positions. Indicates which patches are masked (1) and which aren't (0). + + Returns: + `torch.FloatTensor`: The mean L1 loss between the predicted masks and the ground truth masks. + """ + ground_truth = torch.cat((prompt_masks, labels), dim=2) + + mask = bool_masked_pos[:, :, None].repeat(1, 1, self.patch_size**2 * 3) + mask = unpatchify(mask, ground_truth.shape[2] // self.patch_size, ground_truth.shape[3] // self.patch_size) + + loss = F.smooth_l1_loss(pred_masks, ground_truth, reduction="none", beta=self.beta) + loss = (loss * mask).sum() / mask.sum() # mean loss on removed patches + + return loss + + +@auto_docstring( + custom_intro=""" + SegGpt model with a decoder on top for one-shot image segmentation. + """ +) +class SegGptForImageSegmentation(SegGptPreTrainedModel): + def __init__(self, config: SegGptConfig): + super().__init__(config) + self.config = config + + self.model = SegGptModel(config) + self.decoder = SegGptDecoder(config) + + # Initialize weights and apply final processing + self.post_init() + + @auto_docstring + def forward( + self, + pixel_values: torch.Tensor, + prompt_pixel_values: torch.Tensor, + prompt_masks: torch.Tensor, + bool_masked_pos: torch.BoolTensor | None = None, + feature_ensemble: bool | None = None, + embedding_type: str | None = None, + labels: torch.FloatTensor | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + **kwargs, + ) -> tuple | SegGptImageSegmentationOutput: + r""" + prompt_pixel_values (`torch.FloatTensor` of shape `(batch_size, num_channels, height, width)`): + Prompt pixel values. Prompt pixel values can be obtained using [`AutoImageProcessor`]. See + [`SegGptImageProcessor.__call__`] for details. + prompt_masks (`torch.FloatTensor` of shape `(batch_size, num_channels, height, width)`): + Prompt mask. Prompt mask can be obtained using [`AutoImageProcessor`]. See [`SegGptImageProcessor.__call__`] for + details. + bool_masked_pos (`torch.BoolTensor` of shape `(batch_size, num_patches)`, *optional*): + Boolean masked positions. Indicates which patches are masked (1) and which aren't (0). + feature_ensemble (`bool`, *optional*): + Boolean indicating whether to use feature ensemble or not. If `True`, the model will use feature ensemble + if we have at least two prompts. If `False`, the model will not use feature ensemble. This argument should + be considered when doing few-shot inference on an input image i.e. more than one prompt for the same image. + embedding_type (`str`, *optional*): + Embedding type. Indicates whether the prompt is a semantic or instance embedding. Can be either + instance or semantic. + labels (`torch.FloatTensor` of shape `(batch_size, num_channels, height, width)`, `optional`): + Ground truth mask for input images. + + Examples: + + ```python + >>> from transformers import SegGptImageProcessor, SegGptForImageSegmentation + >>> from PIL import Image + >>> import httpx + >>> from io import BytesIO + + >>> image_input_url = "https://raw.githubusercontent.com/baaivision/Painter/main/SegGPT/SegGPT_inference/examples/hmbb_2.jpg" + >>> image_prompt_url = "https://raw.githubusercontent.com/baaivision/Painter/main/SegGPT/SegGPT_inference/examples/hmbb_1.jpg" + >>> mask_prompt_url = "https://raw.githubusercontent.com/baaivision/Painter/main/SegGPT/SegGPT_inference/examples/hmbb_1_target.png" + + >>> with httpx.stream("GET", image_input_url) as response: + ... image_input = Image.open(BytesIO(response.read())) + + >>> with httpx.stream("GET", image_prompt_url) as response: + ... image_prompt = Image.open(BytesIO(response.read())) + + >>> with httpx.stream("GET", mask_prompt_url) as response: + ... mask_prompt = Image.open(BytesIO(response.read())).convert("L") + + >>> checkpoint = "BAAI/seggpt-vit-large" + >>> model = SegGptForImageSegmentation.from_pretrained(checkpoint) + >>> image_processor = SegGptImageProcessor.from_pretrained(checkpoint) + + >>> inputs = image_processor(images=image_input, prompt_images=image_prompt, prompt_masks=mask_prompt, return_tensors="pt") + >>> outputs = model(**inputs) + >>> result = image_processor.post_process_semantic_segmentation(outputs, target_sizes=[(image_input.height, image_input.width)])[0] + >>> print(list(result.shape)) + [170, 297] + ``` + """ + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + if bool_masked_pos is None: + num_patches = self.model.embeddings.patch_embeddings.num_patches + bool_masked_pos_zeros = torch.zeros(num_patches // 2, dtype=torch.bool, device=pixel_values.device) + bool_masked_pos_ones = torch.ones( + num_patches - num_patches // 2, dtype=torch.bool, device=pixel_values.device + ) + bool_masked_pos = torch.cat([bool_masked_pos_zeros, bool_masked_pos_ones]) + bool_masked_pos = bool_masked_pos.unsqueeze(0) + + outputs = self.model( + pixel_values=pixel_values, + prompt_pixel_values=prompt_pixel_values, + prompt_masks=prompt_masks, + bool_masked_pos=bool_masked_pos, + feature_ensemble=feature_ensemble, + embedding_type=embedding_type, + labels=labels, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + + intermediate_hidden_states = outputs.intermediate_hidden_states if return_dict else outputs[-1] + intermediate_hidden_states = torch.cat(intermediate_hidden_states, dim=-1) + pred_masks = self.decoder(intermediate_hidden_states) + + loss = None + if labels is not None: + loss_fn = SegGptLoss(self.config) + loss = loss_fn(prompt_masks, pred_masks, labels, bool_masked_pos) + + if not return_dict: + output = (pred_masks,) + if output_hidden_states: + output = output + (outputs[1],) + + if output_attentions: + idx = 2 if output_hidden_states else 1 + output = output + (outputs[idx],) + + if loss is not None: + output = (loss,) + output + return output + + return SegGptImageSegmentationOutput( + loss=loss, + pred_masks=pred_masks, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + ) + + +__all__ = ["SegGptModel", "SegGptPreTrainedModel", "SegGptForImageSegmentation"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sew/__init__.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sew/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..0bd614f74a68062d842548bdcba4a65ce19fd62c --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sew/__init__.py @@ -0,0 +1,27 @@ +# Copyright 2024 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from typing import TYPE_CHECKING + +from ...utils import _LazyModule +from ...utils.import_utils import define_import_structure + + +if TYPE_CHECKING: + from .configuration_sew import * + from .modeling_sew import * +else: + import sys + + _file = globals()["__file__"] + sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__) diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sew/configuration_sew.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sew/configuration_sew.py new file mode 100644 index 0000000000000000000000000000000000000000..c636deb29bbee4b12daa68faa4564ea53dc92bb2 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sew/configuration_sew.py @@ -0,0 +1,258 @@ +# Copyright 2021 ASAPP Inc. and The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""SEW model configuration""" + +import functools +import operator + +from ...configuration_utils import PreTrainedConfig +from ...utils import logging + + +logger = logging.get_logger(__name__) + + +class SEWConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`SEWModel`]. It is used to instantiate a SEW model + according to the specified arguments, defining the model architecture. Instantiating a configuration with the + defaults will yield a similar configuration to that of the SEW + [asapp/sew-tiny-100k](https://huggingface.co/asapp/sew-tiny-100k) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + + Args: + vocab_size (`int`, *optional*, defaults to 32): + Vocabulary size of the SEW model. Defines the number of different tokens that can be represented by the + `inputs_ids` passed when calling [`SEW`]. + hidden_size (`int`, *optional*, defaults to 768): + Dimensionality of the encoder layers and the pooler layer. + num_hidden_layers (`int`, *optional*, defaults to 12): + Number of hidden layers in the Transformer encoder. + num_attention_heads (`int`, *optional*, defaults to 12): + Number of attention heads for each attention layer in the Transformer encoder. + intermediate_size (`int`, *optional*, defaults to 3072): + Dimensionality of the "intermediate" (i.e., feed-forward) layer in the Transformer encoder. + squeeze_factor (`int`, *optional*, defaults to 2): + Sequence length downsampling factor after the encoder and upsampling factor after the transformer. + hidden_act (`str` or `function`, *optional*, defaults to `"gelu"`): + The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`, + `"relu"`, `"selu"` and `"gelu_new"` are supported. + hidden_dropout (`float`, *optional*, defaults to 0.1): + The dropout probability for all fully connected layers in the embeddings, encoder, and pooler. + activation_dropout (`float`, *optional*, defaults to 0.1): + The dropout ratio for activations inside the fully connected layer. + attention_dropout (`float`, *optional*, defaults to 0.1): + The dropout ratio for the attention probabilities. + final_dropout (`float`, *optional*, defaults to 0.1): + The dropout probability for the final projection layer of [`SEWForCTC`]. + layerdrop (`float`, *optional*, defaults to 0.1): + The LayerDrop probability. See the [LayerDrop paper](see https://huggingface.co/papers/1909.11556) for more + details. + initializer_range (`float`, *optional*, defaults to 0.02): + The standard deviation of the truncated_normal_initializer for initializing all weight matrices. + layer_norm_eps (`float`, *optional*, defaults to 1e-12): + The epsilon used by the layer normalization layers. + feat_extract_norm (`str`, *optional*, defaults to `"group"`): + The norm to be applied to 1D convolutional layers in feature encoder. One of `"group"` for group + normalization of only the first 1D convolutional layer or `"layer"` for layer normalization of all 1D + convolutional layers. + feat_proj_dropout (`float`, *optional*, defaults to 0.0): + The dropout probability for output of the feature encoder. + feat_extract_activation (`str, `optional`, defaults to `"gelu"`): + The non-linear activation function (function or string) in the 1D convolutional layers of the feature + extractor. If string, `"gelu"`, `"relu"`, `"selu"` and `"gelu_new"` are supported. + conv_dim (`tuple[int]` or `list[int]`, *optional*, defaults to `(64, 128, 128, 128, 128, 256, 256, 256, 256, 512, 512, 512, 512)`): + A tuple of integers defining the number of input and output channels of each 1D convolutional layer in the + feature encoder. The length of *conv_dim* defines the number of 1D convolutional layers. + conv_stride (`tuple[int]` or `list[int]`, *optional*, defaults to `(5, 2, 1, 2, 1, 2, 1, 2, 1, 2, 1, 2, 1)`): + A tuple of integers defining the stride of each 1D convolutional layer in the feature encoder. The length + of *conv_stride* defines the number of convolutional layers and has to match the length of *conv_dim*. + conv_kernel (`tuple[int]` or `list[int]`, *optional*, defaults to `(10, 3, 1, 3, 1, 3, 1, 3, 1, 2, 1, 2, 1)`): + A tuple of integers defining the kernel size of each 1D convolutional layer in the feature encoder. The + length of *conv_kernel* defines the number of convolutional layers and has to match the length of + *conv_dim*. + conv_bias (`bool`, *optional*, defaults to `False`): + Whether the 1D convolutional layers have a bias. + num_conv_pos_embeddings (`int`, *optional*, defaults to 128): + Number of convolutional positional embeddings. Defines the kernel size of 1D convolutional positional + embeddings layer. + num_conv_pos_embedding_groups (`int`, *optional*, defaults to 16): + Number of groups of 1D convolutional positional embeddings layer. + apply_spec_augment (`bool`, *optional*, defaults to `True`): + Whether to apply *SpecAugment* data augmentation to the outputs of the feature encoder. For reference see + [SpecAugment: A Simple Data Augmentation Method for Automatic Speech + Recognition](https://huggingface.co/papers/1904.08779). + mask_time_prob (`float`, *optional*, defaults to 0.05): + Percentage (between 0 and 1) of all feature vectors along the time axis which will be masked. The masking + procedure generates ''mask_time_prob*len(time_axis)/mask_time_length'' independent masks over the axis. If + reasoning from the probability of each feature vector to be chosen as the start of the vector span to be + masked, *mask_time_prob* should be `prob_vector_start*mask_time_length`. Note that overlap may decrease the + actual percentage of masked vectors. This is only relevant if `apply_spec_augment is True`. + mask_time_length (`int`, *optional*, defaults to 10): + Length of vector span along the time axis. + mask_time_min_masks (`int`, *optional*, defaults to 2),: + The minimum number of masks of length `mask_feature_length` generated along the time axis, each time step, + irrespectively of `mask_feature_prob`. Only relevant if ''mask_time_prob*len(time_axis)/mask_time_length < + mask_time_min_masks'' + mask_feature_prob (`float`, *optional*, defaults to 0.0): + Percentage (between 0 and 1) of all feature vectors along the feature axis which will be masked. The + masking procedure generates ''mask_feature_prob*len(feature_axis)/mask_time_length'' independent masks over + the axis. If reasoning from the probability of each feature vector to be chosen as the start of the vector + span to be masked, *mask_feature_prob* should be `prob_vector_start*mask_feature_length`. Note that overlap + may decrease the actual percentage of masked vectors. This is only relevant if `apply_spec_augment is + True`. + mask_feature_length (`int`, *optional*, defaults to 10): + Length of vector span along the feature axis. + mask_feature_min_masks (`int`, *optional*, defaults to 0),: + The minimum number of masks of length `mask_feature_length` generated along the feature axis, each time + step, irrespectively of `mask_feature_prob`. Only relevant if + ''mask_feature_prob*len(feature_axis)/mask_feature_length < mask_feature_min_masks'' + ctc_loss_reduction (`str`, *optional*, defaults to `"sum"`): + Specifies the reduction to apply to the output of `torch.nn.CTCLoss`. Only relevant when training an + instance of [`SEWForCTC`]. + ctc_zero_infinity (`bool`, *optional*, defaults to `False`): + Whether to zero infinite losses and the associated gradients of `torch.nn.CTCLoss`. Infinite losses mainly + occur when the inputs are too short to be aligned to the targets. Only relevant when training an instance + of [`SEWForCTC`]. + use_weighted_layer_sum (`bool`, *optional*, defaults to `False`): + Whether to use a weighted average of layer outputs with learned weights. Only relevant when using an + instance of [`Wav2Vec2ForSequenceClassification`]. + classifier_proj_size (`int`, *optional*, defaults to 256): + Dimensionality of the projection before token mean-pooling for classification. + + Example: + + ```python + >>> from transformers import SEWConfig, SEWModel + + >>> # Initializing a SEW asapp/sew-tiny-100k style configuration + >>> configuration = SEWConfig() + + >>> # Initializing a model (with random weights) from the asapp/sew-tiny-100k style configuration + >>> model = SEWModel(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "sew" + + def __init__( + self, + vocab_size=32, + hidden_size=768, + num_hidden_layers=12, + num_attention_heads=12, + intermediate_size=3072, + squeeze_factor=2, + hidden_act="gelu", + hidden_dropout=0.1, + activation_dropout=0.1, + attention_dropout=0.1, + feat_proj_dropout=0.0, + final_dropout=0.1, + layerdrop=0.1, + initializer_range=0.02, + layer_norm_eps=1e-5, + feat_extract_norm="group", + feat_extract_activation="gelu", + conv_dim=(64, 128, 128, 128, 128, 256, 256, 256, 256, 512, 512, 512, 512), + conv_stride=(5, 2, 1, 2, 1, 2, 1, 2, 1, 2, 1, 2, 1), + conv_kernel=(10, 3, 1, 3, 1, 3, 1, 3, 1, 2, 1, 2, 1), + conv_bias=False, + num_conv_pos_embeddings=128, + num_conv_pos_embedding_groups=16, + apply_spec_augment=True, + mask_time_prob=0.05, + mask_time_length=10, + mask_time_min_masks=2, + mask_feature_prob=0.0, + mask_feature_length=10, + mask_feature_min_masks=0, + ctc_loss_reduction="mean", + ctc_zero_infinity=False, + use_weighted_layer_sum=False, + classifier_proj_size=256, + pad_token_id=0, + bos_token_id=1, + eos_token_id=2, + **kwargs, + ): + super().__init__(**kwargs) + self.pad_token_id = pad_token_id + self.bos_token_id = bos_token_id + self.eos_token_id = eos_token_id + self.hidden_size = hidden_size + self.feat_extract_norm = feat_extract_norm + self.feat_extract_activation = feat_extract_activation + self.conv_dim = list(conv_dim) + self.conv_stride = list(conv_stride) + self.conv_kernel = list(conv_kernel) + self.conv_bias = conv_bias + self.num_conv_pos_embeddings = num_conv_pos_embeddings + self.num_conv_pos_embedding_groups = num_conv_pos_embedding_groups + self.num_feat_extract_layers = len(self.conv_dim) + self.num_hidden_layers = num_hidden_layers + self.intermediate_size = intermediate_size + self.squeeze_factor = squeeze_factor + self.hidden_act = hidden_act + self.num_attention_heads = num_attention_heads + self.hidden_dropout = hidden_dropout + self.attention_dropout = attention_dropout + self.activation_dropout = activation_dropout + self.feat_proj_dropout = feat_proj_dropout + self.final_dropout = final_dropout + self.layerdrop = layerdrop + self.layer_norm_eps = layer_norm_eps + self.initializer_range = initializer_range + self.vocab_size = vocab_size + + if ( + (len(self.conv_stride) != self.num_feat_extract_layers) + or (len(self.conv_kernel) != self.num_feat_extract_layers) + or (len(self.conv_dim) != self.num_feat_extract_layers) + ): + raise ValueError( + "Configuration for convolutional layers is incorrect. " + "It is required that `len(config.conv_dim)` == `len(config.conv_stride)` == `len(config.conv_kernel)`, " + f"but is `len(config.conv_dim) = {len(self.conv_dim)}`, `len(config.conv_stride) " + f"= {len(self.conv_stride)}`, `len(config.conv_kernel) = {len(self.conv_kernel)}`." + ) + + # fine-tuning config parameters for SpecAugment: https://huggingface.co/papers/1904.08779 + self.apply_spec_augment = apply_spec_augment + self.mask_time_prob = mask_time_prob + self.mask_time_length = mask_time_length + self.mask_time_min_masks = mask_time_min_masks + self.mask_feature_prob = mask_feature_prob + self.mask_feature_length = mask_feature_length + self.mask_feature_min_masks = mask_feature_min_masks + + # ctc loss + self.ctc_loss_reduction = ctc_loss_reduction + self.ctc_zero_infinity = ctc_zero_infinity + + # sequence classification + self.use_weighted_layer_sum = use_weighted_layer_sum + self.classifier_proj_size = classifier_proj_size + + @property + def inputs_to_logits_ratio(self): + return functools.reduce(operator.mul, self.conv_stride, 1) + + +__all__ = ["SEWConfig"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sew/modeling_sew.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sew/modeling_sew.py new file mode 100644 index 0000000000000000000000000000000000000000..8f70f51e390933089805e71a4a8608992966cfda --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sew/modeling_sew.py @@ -0,0 +1,1081 @@ +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# This file was automatically generated from src/transformers/models/sew/modular_sew.py. +# Do NOT edit this file manually as any edits will be overwritten by the generation of +# the file from the modular. If any change should be done, please apply the change to the +# modular_sew.py file directly. One of our CI enforces this. +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# Copyright 2021 ASAPP Inc. and the HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import math +from collections.abc import Callable + +import numpy as np +import torch +from torch import nn +from torch.nn import CrossEntropyLoss + +from ... import initialization as init +from ...activations import ACT2FN +from ...integrations.deepspeed import is_deepspeed_zero3_enabled +from ...integrations.fsdp import is_fsdp_managed_module +from ...modeling_flash_attention_utils import FlashAttentionKwargs +from ...modeling_layers import GradientCheckpointingLayer +from ...modeling_outputs import BaseModelOutput, CausalLMOutput, SequenceClassifierOutput +from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel, get_torch_context_manager_or_global_device +from ...processing_utils import Unpack +from ...utils import TransformersKwargs, auto_docstring, logging +from ...utils.generic import is_flash_attention_requested +from .configuration_sew import SEWConfig + + +logger = logging.get_logger(__name__) + + +class SEWNoLayerNormConvLayer(GradientCheckpointingLayer): + def __init__(self, config, layer_id=0): + super().__init__() + self.in_conv_dim = config.conv_dim[layer_id - 1] if layer_id > 0 else 1 + self.out_conv_dim = config.conv_dim[layer_id] + + self.conv = nn.Conv1d( + self.in_conv_dim, + self.out_conv_dim, + kernel_size=config.conv_kernel[layer_id], + stride=config.conv_stride[layer_id], + bias=config.conv_bias, + ) + self.activation = ACT2FN[config.feat_extract_activation] + + def forward(self, hidden_states): + hidden_states = self.conv(hidden_states) + hidden_states = self.activation(hidden_states) + return hidden_states + + +class SEWLayerNormConvLayer(GradientCheckpointingLayer): + def __init__(self, config, layer_id=0): + super().__init__() + self.in_conv_dim = config.conv_dim[layer_id - 1] if layer_id > 0 else 1 + self.out_conv_dim = config.conv_dim[layer_id] + + self.conv = nn.Conv1d( + self.in_conv_dim, + self.out_conv_dim, + kernel_size=config.conv_kernel[layer_id], + stride=config.conv_stride[layer_id], + bias=config.conv_bias, + ) + self.layer_norm = nn.LayerNorm(self.out_conv_dim, elementwise_affine=True) + self.activation = ACT2FN[config.feat_extract_activation] + + def forward(self, hidden_states): + hidden_states = self.conv(hidden_states) + + hidden_states = hidden_states.transpose(-2, -1) + hidden_states = self.layer_norm(hidden_states) + hidden_states = hidden_states.transpose(-2, -1) + + hidden_states = self.activation(hidden_states) + return hidden_states + + +class SEWGroupNormConvLayer(GradientCheckpointingLayer): + def __init__(self, config, layer_id=0): + super().__init__() + self.in_conv_dim = config.conv_dim[layer_id - 1] if layer_id > 0 else 1 + self.out_conv_dim = config.conv_dim[layer_id] + + self.conv = nn.Conv1d( + self.in_conv_dim, + self.out_conv_dim, + kernel_size=config.conv_kernel[layer_id], + stride=config.conv_stride[layer_id], + bias=config.conv_bias, + ) + self.activation = ACT2FN[config.feat_extract_activation] + + self.layer_norm = nn.GroupNorm(num_groups=self.out_conv_dim, num_channels=self.out_conv_dim, affine=True) + + def forward(self, hidden_states): + hidden_states = self.conv(hidden_states) + hidden_states = self.layer_norm(hidden_states) + hidden_states = self.activation(hidden_states) + return hidden_states + + +class SEWPositionalConvEmbedding(nn.Module): + def __init__(self, config): + super().__init__() + self.conv = nn.Conv1d( + config.hidden_size, + config.hidden_size, + kernel_size=config.num_conv_pos_embeddings, + padding=config.num_conv_pos_embeddings // 2, + groups=config.num_conv_pos_embedding_groups, + stride=config.squeeze_factor, + ) + + weight_norm = nn.utils.weight_norm + if hasattr(nn.utils.parametrizations, "weight_norm"): + weight_norm = nn.utils.parametrizations.weight_norm + + if is_deepspeed_zero3_enabled(): + import deepspeed + + with deepspeed.zero.GatheredParameters(self.conv.weight, modifier_rank=0): + self.conv = weight_norm(self.conv, name="weight", dim=2) + if hasattr(self.conv, "parametrizations"): + weight_g = self.conv.parametrizations.weight.original0 + weight_v = self.conv.parametrizations.weight.original1 + else: + weight_g = self.conv.weight_g + weight_v = self.conv.weight_v + deepspeed.zero.register_external_parameter(self, weight_v) + deepspeed.zero.register_external_parameter(self, weight_g) + else: + self.conv = weight_norm(self.conv, name="weight", dim=2) + + self.padding = SEWSamePadLayer(config.num_conv_pos_embeddings) + self.activation = ACT2FN[config.feat_extract_activation] + + def forward(self, hidden_states): + hidden_states = self.conv(hidden_states) + hidden_states = self.padding(hidden_states) + hidden_states = self.activation(hidden_states) + + return hidden_states + + +class SEWSamePadLayer(nn.Module): + def __init__(self, num_conv_pos_embeddings): + super().__init__() + self.num_pad_remove = 1 if num_conv_pos_embeddings % 2 == 0 else 0 + + def forward(self, hidden_states): + if self.num_pad_remove > 0: + hidden_states = hidden_states[:, :, : -self.num_pad_remove] + return hidden_states + + +class SEWUpsampling(nn.Module): + def __init__(self, config): + super().__init__() + self.projection = nn.Linear(config.hidden_size, config.hidden_size * config.squeeze_factor) + self.activation = ACT2FN[config.feat_extract_activation] + self.squeeze_factor = config.squeeze_factor + + def forward(self, hidden_states): + hidden_states = self.projection(hidden_states) + hidden_states = self.activation(hidden_states) + + if self.squeeze_factor > 1: + # transform embedding channels to sequence length + bsz, src_len, src_embed_dim = hidden_states.size() + tgt_len = src_len * self.squeeze_factor + tgt_embed_dim = src_embed_dim // self.squeeze_factor + hidden_states = hidden_states.reshape(bsz, src_len, self.squeeze_factor, tgt_embed_dim) + hidden_states = hidden_states.reshape(bsz, tgt_len, tgt_embed_dim) + + return hidden_states + + +class SEWFeatureEncoder(nn.Module): + """Construct the features from raw audio waveform""" + + def __init__(self, config): + super().__init__() + + if config.feat_extract_norm == "group": + conv_layers = [SEWGroupNormConvLayer(config, layer_id=0)] + [ + SEWNoLayerNormConvLayer(config, layer_id=i + 1) for i in range(config.num_feat_extract_layers - 1) + ] + elif config.feat_extract_norm == "layer": + conv_layers = [SEWLayerNormConvLayer(config, layer_id=i) for i in range(config.num_feat_extract_layers)] + else: + raise ValueError( + f"`config.feat_extract_norm` is {config.feat_extract_norm}, but has to be one of ['group', 'layer']" + ) + self.conv_layers = nn.ModuleList(conv_layers) + self.gradient_checkpointing = False + self._requires_grad = True + + def _freeze_parameters(self): + for param in self.parameters(): + param.requires_grad = False + self._requires_grad = False + + def forward(self, input_values): + hidden_states = input_values[:, None] + + # make sure hidden_states require grad for gradient_checkpointing + if self._requires_grad and self.training: + hidden_states.requires_grad = True + + for conv_layer in self.conv_layers: + hidden_states = conv_layer(hidden_states) + + return hidden_states + + +def eager_attention_forward( + module: nn.Module, + query: torch.Tensor, + key: torch.Tensor, + value: torch.Tensor, + attention_mask: torch.Tensor | None, + scaling: float | None = None, + dropout: float = 0.0, + **kwargs: Unpack[TransformersKwargs], +): + if scaling is None: + scaling = query.size(-1) ** -0.5 + + # Take the dot product between "query" and "key" to get the raw attention scores. + attn_weights = torch.matmul(query, key.transpose(2, 3)) * scaling + + if attention_mask is not None: + attn_weights = attn_weights + attention_mask + + attn_weights = nn.functional.softmax(attn_weights, dim=-1) + attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training) + + attn_output = torch.matmul(attn_weights, value) + attn_output = attn_output.transpose(1, 2).contiguous() + + return attn_output, attn_weights + + +class SEWAttention(nn.Module): + """Multi-headed attention from 'Attention Is All You Need' paper""" + + def __init__( + self, + embed_dim: int, + num_heads: int, + dropout: float = 0.0, + is_decoder: bool = False, + bias: bool = True, + is_causal: bool = False, + config: SEWConfig | None = None, + ): + super().__init__() + self.embed_dim = embed_dim + self.num_heads = num_heads + self.dropout = dropout + self.head_dim = embed_dim // num_heads + self.config = config + + if (self.head_dim * num_heads) != self.embed_dim: + raise ValueError( + f"embed_dim must be divisible by num_heads (got `embed_dim`: {self.embed_dim}" + f" and `num_heads`: {num_heads})." + ) + self.scaling = self.head_dim**-0.5 + self.is_decoder = is_decoder + self.is_causal = is_causal + + self.k_proj = nn.Linear(embed_dim, embed_dim, bias=bias) + self.v_proj = nn.Linear(embed_dim, embed_dim, bias=bias) + self.q_proj = nn.Linear(embed_dim, embed_dim, bias=bias) + self.out_proj = nn.Linear(embed_dim, embed_dim, bias=bias) + + def forward( + self, + hidden_states: torch.Tensor, + key_value_states: torch.Tensor | None = None, + attention_mask: torch.Tensor | None = None, + output_attentions: bool | None = False, + # TODO: we need a refactor so that the different attention modules can get their specific kwargs + # ATM, we have mixed things encoder, decoder, and encoder-decoder attn + **kwargs: Unpack[FlashAttentionKwargs], + ) -> tuple[torch.Tensor, torch.Tensor | None, tuple[torch.Tensor] | None]: + """Input shape: Batch x Time x Channel""" + + # if key_value_states are provided this layer is used as a cross-attention layer + # for the decoder + is_cross_attention = key_value_states is not None + + # determine input shapes + bsz, tgt_len = hidden_states.shape[:-1] + src_len = key_value_states.shape[1] if is_cross_attention else tgt_len + + q_input_shape = (bsz, tgt_len, -1, self.head_dim) + kv_input_shape = (bsz, src_len, -1, self.head_dim) + + # get query proj + query_states = self.q_proj(hidden_states).view(*q_input_shape).transpose(1, 2) + + current_states = key_value_states if is_cross_attention else hidden_states + key_states = self.k_proj(current_states).view(*kv_input_shape).transpose(1, 2) + value_states = self.v_proj(current_states).view(*kv_input_shape).transpose(1, 2) + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, eager_attention_forward + ) + + attn_output, attn_weights = attention_interface( + self, + query_states, + key_states, + value_states, + attention_mask, + dropout=0.0 if not self.training else self.dropout, + scaling=self.scaling, + output_attentions=output_attentions, + **kwargs, + ) + + attn_output = attn_output.reshape(bsz, tgt_len, -1).contiguous() + attn_output = self.out_proj(attn_output) + + return attn_output, attn_weights, None + + +class SEWFeedForward(nn.Module): + def __init__(self, config): + super().__init__() + self.intermediate_dropout = nn.Dropout(config.activation_dropout) + + self.intermediate_dense = nn.Linear(config.hidden_size, config.intermediate_size) + if isinstance(config.hidden_act, str): + self.intermediate_act_fn = ACT2FN[config.hidden_act] + else: + self.intermediate_act_fn = config.hidden_act + + self.output_dense = nn.Linear(config.intermediate_size, config.hidden_size) + self.output_dropout = nn.Dropout(config.hidden_dropout) + + def forward(self, hidden_states): + hidden_states = self.intermediate_dense(hidden_states) + hidden_states = self.intermediate_act_fn(hidden_states) + hidden_states = self.intermediate_dropout(hidden_states) + + hidden_states = self.output_dense(hidden_states) + hidden_states = self.output_dropout(hidden_states) + return hidden_states + + +class SEWEncoderLayer(GradientCheckpointingLayer): + def __init__(self, config): + super().__init__() + self.attention = SEWAttention( + embed_dim=config.hidden_size, + num_heads=config.num_attention_heads, + dropout=config.attention_dropout, + is_decoder=False, + config=config, + ) + + self.dropout = nn.Dropout(config.hidden_dropout) + self.layer_norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps) + self.feed_forward = SEWFeedForward(config) + self.final_layer_norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps) + + def forward(self, hidden_states, attention_mask=None, output_attentions=False): + attn_residual = hidden_states + hidden_states, attn_weights, _ = self.attention( + hidden_states, attention_mask=attention_mask, output_attentions=output_attentions + ) + hidden_states = self.dropout(hidden_states) + hidden_states = attn_residual + hidden_states + + hidden_states = self.layer_norm(hidden_states) + hidden_states = hidden_states + self.feed_forward(hidden_states) + hidden_states = self.final_layer_norm(hidden_states) + + outputs = (hidden_states,) + + if output_attentions: + outputs += (attn_weights,) + + return outputs + + +class SEWEncoder(nn.Module): + def __init__(self, config): + super().__init__() + self.config = config + self.pos_conv_embed = SEWPositionalConvEmbedding(config) + self.pool = nn.AvgPool1d(config.squeeze_factor, config.squeeze_factor) + self.layer_norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps) + self.dropout = nn.Dropout(config.hidden_dropout) + self.layers = nn.ModuleList([SEWEncoderLayer(config) for _ in range(config.num_hidden_layers)]) + self.upsample = SEWUpsampling(config) + self.gradient_checkpointing = False + + def forward( + self, + hidden_states, + attention_mask=None, + output_attentions=False, + output_hidden_states=False, + return_dict=True, + ): + all_hidden_states = () if output_hidden_states else None + all_self_attentions = () if output_attentions else None + + if attention_mask is not None: + expand_attention_mask = attention_mask.unsqueeze(-1).repeat(1, 1, hidden_states.shape[2]) + if is_flash_attention_requested(self.config): + # make sure padded tokens output 0 + hidden_states[~expand_attention_mask] = 0.0 + # 2d mask is passed through the layers + attention_mask = attention_mask if (attention_mask is not None and 0 in attention_mask) else None + else: + # make sure padded tokens output 0 + hidden_states[~expand_attention_mask] = 0.0 + input_lengths = (attention_mask.long()).sum(-1) + # apply pooling formula to get real output_lengths + output_lengths = input_lengths // self.config.squeeze_factor + max_encoder_length = hidden_states.shape[1] // self.config.squeeze_factor + attention_ids = ( + torch.arange(0, max_encoder_length, device=output_lengths.device) + .view(1, -1) + .expand(output_lengths.shape[0], -1) + ) + attention_mask = (attention_ids < output_lengths.view(-1, 1)).long() + + # extend attention_mask + attention_mask = 1.0 - attention_mask[:, None, None, :].to(dtype=hidden_states.dtype) + attention_mask = attention_mask * torch.finfo(hidden_states.dtype).min + attention_mask = attention_mask.expand( + attention_mask.shape[0], 1, attention_mask.shape[-1], attention_mask.shape[-1] + ) + + n_input_timesteps = hidden_states.shape[1] + + hidden_states = hidden_states.transpose(1, 2) + position_embeddings = self.pos_conv_embed(hidden_states) + pooled_hidden_states = self.pool(hidden_states) + min_length = min(position_embeddings.size(-1), pooled_hidden_states.size(-1)) + hidden_states = pooled_hidden_states[..., :min_length] + position_embeddings[..., :min_length] + hidden_states = hidden_states.transpose(1, 2) + + hidden_states = self.layer_norm(hidden_states) + hidden_states = self.dropout(hidden_states) + + synced_gpus = is_deepspeed_zero3_enabled() or is_fsdp_managed_module(self) + + for layer in self.layers: + if output_hidden_states: + all_hidden_states = all_hidden_states + (hidden_states,) + + # add LayerDrop (see https://huggingface.co/papers/1909.11556 for description) + dropout_probability = torch.rand([]) + + skip_the_layer = self.training and dropout_probability < self.config.layerdrop + if not skip_the_layer or synced_gpus: + # under fsdp or deepspeed zero3 all gpus must run in sync + layer_outputs = layer( + hidden_states, attention_mask=attention_mask, output_attentions=output_attentions + ) + hidden_states = layer_outputs[0] + + if skip_the_layer: + layer_outputs = (None, None) + + if output_attentions: + all_self_attentions = all_self_attentions + (layer_outputs[1],) + + if output_hidden_states: + all_hidden_states = all_hidden_states + (hidden_states,) + + hidden_states = self.upsample(hidden_states) + if hidden_states.shape[1] < n_input_timesteps: + hidden_states = nn.functional.pad(hidden_states, (0, 0, 0, n_input_timesteps - hidden_states.shape[1])) + + if not return_dict: + return tuple(v for v in [hidden_states, all_hidden_states, all_self_attentions] if v is not None) + return BaseModelOutput( + last_hidden_state=hidden_states, + hidden_states=all_hidden_states, + attentions=all_self_attentions, + ) + + +@auto_docstring +class SEWPreTrainedModel(PreTrainedModel): + config: SEWConfig + base_model_prefix = "sew" + main_input_name = "input_values" + input_modalities = "audio" + supports_gradient_checkpointing = True + _supports_flash_attn = True + _supports_sdpa = True + _supports_flex_attn = False # needs a proper look into the mask creation + + @torch.no_grad() + def _init_weights(self, module): + """Initialize the weights""" + if isinstance(module, SEWPositionalConvEmbedding): + init.normal_( + module.conv.weight, + mean=0, + std=2 * math.sqrt(1 / (module.conv.kernel_size[0] * module.conv.in_channels)), + ) + init.constant_(module.conv.bias, 0) + elif isinstance(module, nn.Linear): + init.normal_(module.weight, mean=0.0, std=self.config.initializer_range) + elif isinstance(module, (nn.LayerNorm, nn.GroupNorm)): + init.zeros_(module.bias) + init.ones_(module.weight) + elif isinstance(module, nn.Conv1d): + if is_deepspeed_zero3_enabled(): + import deepspeed + + if hasattr(module, "weight_v") and hasattr(module, "weight_g"): + with deepspeed.zero.GatheredParameters([module.weight_v, module.weight_g], modifier_rank=0): + init.kaiming_normal_(module.weight) + else: + with deepspeed.zero.GatheredParameters(module.weight, modifier_rank=0): + init.kaiming_normal_(module.weight) + else: + init.kaiming_normal_(module.weight) + + if isinstance(module, (nn.Linear, nn.Conv1d)) and module.bias is not None: + init.zeros_(module.bias) + + def _get_feat_extract_output_lengths(self, input_lengths: torch.LongTensor | int): + """ + Computes the output length of the convolutional layers + """ + + def _conv_out_length(input_length, kernel_size, stride): + # 1D convolutional layer output length formula taken + # from https://pytorch.org/docs/stable/generated/torch.nn.Conv1d.html + return torch.div(input_length - kernel_size, stride, rounding_mode="floor") + 1 + + for kernel_size, stride in zip(self.config.conv_kernel, self.config.conv_stride): + input_lengths = _conv_out_length(input_lengths, kernel_size, stride) + + return input_lengths + + def _get_feature_vector_attention_mask(self, feature_vector_length: int, attention_mask: torch.LongTensor): + output_lengths = self._get_feat_extract_output_lengths(attention_mask.sum(-1)).to(torch.long) + batch_size = attention_mask.shape[0] + + attention_mask = torch.zeros( + (batch_size, feature_vector_length), dtype=attention_mask.dtype, device=attention_mask.device + ) + # these two operations makes sure that all values before the output lengths idxs are attended to + attention_mask[(torch.arange(attention_mask.shape[0], device=attention_mask.device), output_lengths - 1)] = 1 + attention_mask = attention_mask.flip([-1]).cumsum(-1).flip([-1]).bool() + return attention_mask + + +def _compute_mask_indices( + shape: tuple[int, int], + mask_prob: float, + mask_length: int, + attention_mask: torch.LongTensor | None = None, + min_masks: int = 0, +) -> np.ndarray: + """ + Computes random mask spans for a given shape. Used to implement [SpecAugment: A Simple Data Augmentation Method for + ASR](https://huggingface.co/papers/1904.08779). Note that this method is not optimized to run on TPU and should be run on + CPU as part of the preprocessing during training. + + Args: + shape: The shape for which to compute masks. This should be of a tuple of size 2 where + the first element is the batch size and the second element is the length of the axis to span. + mask_prob: The percentage of the whole axis (between 0 and 1) which will be masked. The number of + independently generated mask spans of length `mask_length` is computed by + `mask_prob*shape[1]/mask_length`. Note that due to overlaps, `mask_prob` is an upper bound and the + actual percentage will be smaller. + mask_length: size of the mask + min_masks: minimum number of masked spans + attention_mask: A (right-padded) attention mask which independently shortens the feature axis of + each batch dimension. + """ + batch_size, sequence_length = shape + + if mask_length < 1: + raise ValueError("`mask_length` has to be bigger than 0.") + + if mask_length > sequence_length: + raise ValueError( + f"`mask_length` has to be smaller than `sequence_length`, but got `mask_length`: {mask_length}" + f" and `sequence_length`: {sequence_length}`" + ) + + # epsilon is used for probabilistic rounding + epsilon = np.random.rand(1).item() + + def compute_num_masked_span(input_length): + """Given input length, compute how many spans should be masked""" + num_masked_span = int(mask_prob * input_length / mask_length + epsilon) + num_masked_span = max(num_masked_span, min_masks) + + # make sure num masked span <= sequence_length + if num_masked_span * mask_length > sequence_length: + num_masked_span = sequence_length // mask_length + + # make sure num_masked span is also <= input_length - (mask_length - 1) + if input_length - (mask_length - 1) < num_masked_span: + num_masked_span = max(input_length - (mask_length - 1), 0) + + return num_masked_span + + # compute number of masked spans in batch + input_lengths = ( + attention_mask.detach().sum(-1).tolist() + if attention_mask is not None + else [sequence_length for _ in range(batch_size)] + ) + + # SpecAugment mask to fill + spec_aug_mask = np.zeros((batch_size, sequence_length), dtype=bool) + spec_aug_mask_idxs = [] + + max_num_masked_span = compute_num_masked_span(sequence_length) + + if max_num_masked_span == 0: + return spec_aug_mask + + for input_length in input_lengths: + # compute num of masked spans for this input + num_masked_span = compute_num_masked_span(input_length) + + # get random indices to mask + spec_aug_mask_idx = np.random.choice( + np.arange(input_length - (mask_length - 1)), num_masked_span, replace=False + ) + + # pick first sampled index that will serve as a dummy index to pad vector + # to ensure same dimension for all batches due to probabilistic rounding + # Picking first sample just pads those vectors twice. + if len(spec_aug_mask_idx) == 0: + # this case can only happen if `input_length` is strictly smaller then + # `sequence_length` in which case the last token has to be a padding + # token which we can use as a dummy mask id + dummy_mask_idx = sequence_length - 1 + else: + dummy_mask_idx = spec_aug_mask_idx[0] + + spec_aug_mask_idx = np.concatenate( + [spec_aug_mask_idx, np.ones(max_num_masked_span - num_masked_span, dtype=np.int32) * dummy_mask_idx] + ) + spec_aug_mask_idxs.append(spec_aug_mask_idx) + + spec_aug_mask_idxs = np.array(spec_aug_mask_idxs) + + # expand masked indices to masked spans + spec_aug_mask_idxs = np.broadcast_to( + spec_aug_mask_idxs[:, :, None], (batch_size, max_num_masked_span, mask_length) + ) + spec_aug_mask_idxs = spec_aug_mask_idxs.reshape(batch_size, max_num_masked_span * mask_length) + + # add offset to the starting indexes so that indexes now create a span + offsets = np.arange(mask_length)[None, None, :] + offsets = np.broadcast_to(offsets, (batch_size, max_num_masked_span, mask_length)).reshape( + batch_size, max_num_masked_span * mask_length + ) + spec_aug_mask_idxs = spec_aug_mask_idxs + offsets + + # ensure that we cannot have indices larger than sequence_length + if spec_aug_mask_idxs.max() > sequence_length - 1: + spec_aug_mask_idxs[spec_aug_mask_idxs > sequence_length - 1] = sequence_length - 1 + + # scatter indices to mask + np.put_along_axis(spec_aug_mask, spec_aug_mask_idxs, 1, -1) + + return spec_aug_mask + + +@auto_docstring +class SEWModel(SEWPreTrainedModel): + def __init__(self, config: SEWConfig): + super().__init__(config) + self.config = config + self.feature_extractor = SEWFeatureEncoder(config) + self.layer_norm = nn.LayerNorm(config.conv_dim[-1], eps=config.layer_norm_eps) + + self.project_features = config.conv_dim[-1] != config.hidden_size + if self.project_features: + self.feature_projection = nn.Linear(config.conv_dim[-1], config.hidden_size) + self.feature_dropout = nn.Dropout(config.feat_proj_dropout) + + if config.mask_time_prob > 0.0 or config.mask_feature_prob > 0.0: + self.masked_spec_embed = nn.Parameter(torch.Tensor(config.hidden_size).uniform_()) + + self.encoder = SEWEncoder(config) + + # Initialize weights and apply final processing + self.post_init() + + # Copied from transformers.models.wav2vec2.modeling_wav2vec2.Wav2Vec2Model._mask_hidden_states + def _mask_hidden_states( + self, + hidden_states: torch.FloatTensor, + mask_time_indices: torch.FloatTensor | None = None, + attention_mask: torch.LongTensor | None = None, + ): + """ + Masks extracted features along time axis and/or along feature axis according to + [SpecAugment](https://huggingface.co/papers/1904.08779). + """ + + # `config.apply_spec_augment` can set masking to False + if not getattr(self.config, "apply_spec_augment", True): + return hidden_states + + # generate indices & apply SpecAugment along time axis + batch_size, sequence_length, hidden_size = hidden_states.size() + + if mask_time_indices is not None: + # apply SpecAugment along time axis with given mask_time_indices + hidden_states[mask_time_indices] = self.masked_spec_embed.to(hidden_states.dtype) + elif self.config.mask_time_prob > 0 and self.training: + mask_time_indices = _compute_mask_indices( + (batch_size, sequence_length), + mask_prob=self.config.mask_time_prob, + mask_length=self.config.mask_time_length, + attention_mask=attention_mask, + min_masks=self.config.mask_time_min_masks, + ) + mask_time_indices = torch.tensor(mask_time_indices, device=hidden_states.device, dtype=torch.bool) + hidden_states[mask_time_indices] = self.masked_spec_embed.to(hidden_states.dtype) + + if self.config.mask_feature_prob > 0 and self.training: + # generate indices & apply SpecAugment along feature axis + mask_feature_indices = _compute_mask_indices( + (batch_size, hidden_size), + mask_prob=self.config.mask_feature_prob, + mask_length=self.config.mask_feature_length, + min_masks=self.config.mask_feature_min_masks, + ) + mask_feature_indices = torch.tensor(mask_feature_indices, device=hidden_states.device, dtype=torch.bool) + mask_feature_indices = mask_feature_indices[:, None].expand(-1, sequence_length, -1) + hidden_states[mask_feature_indices] = 0 + + return hidden_states + + @auto_docstring + def forward( + self, + input_values: torch.Tensor | None, + attention_mask: torch.Tensor | None = None, + mask_time_indices: torch.FloatTensor | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + **kwargs, + ) -> tuple | BaseModelOutput: + r""" + mask_time_indices (`torch.BoolTensor` of shape `(batch_size, sequence_length)`, *optional*): + Indices to mask extracted features for contrastive loss. When in training mode, model learns to predict + masked extracted features in *config.proj_codevector_dim* space. + """ + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + extract_features = self.feature_extractor(input_values) + extract_features = extract_features.transpose(1, 2) + extract_features = self.layer_norm(extract_features) + + if self.project_features: + extract_features = self.feature_projection(extract_features) + hidden_states = self.feature_dropout(extract_features) + + if attention_mask is not None: + # compute reduced attention_mask corresponding to feature vectors + attention_mask = self._get_feature_vector_attention_mask(hidden_states.shape[1], attention_mask) + + hidden_states = self._mask_hidden_states(hidden_states, mask_time_indices=mask_time_indices) + + encoder_outputs = self.encoder( + hidden_states, + attention_mask=attention_mask, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + + hidden_states = encoder_outputs[0] + + if not return_dict: + return (hidden_states,) + encoder_outputs[1:] + + return BaseModelOutput( + last_hidden_state=hidden_states, + hidden_states=encoder_outputs.hidden_states, + attentions=encoder_outputs.attentions, + ) + + +_HIDDEN_STATES_START_POSITION = 1 + + +@auto_docstring( + custom_intro=""" + SEW Model with a `language modeling` head on top for Connectionist Temporal Classification (CTC). + """ +) +class SEWForCTC(SEWPreTrainedModel): + def __init__(self, config, target_lang: str | None = None): + r""" + target_lang (`str`, *optional*): + Language id of adapter weights. Adapter weights are stored in the format adapter..safetensors or + adapter..bin. Only relevant when using an instance of [`SEWForCTC`] with adapters. Uses 'eng' by + default. + """ + super().__init__(config) + + self.sew = SEWModel(config) + self.dropout = nn.Dropout(config.final_dropout) + + self.target_lang = target_lang + + if config.vocab_size is None: + raise ValueError( + f"You are trying to instantiate {self.__class__} with a configuration that " + "does not define the vocabulary size of the language model head. Please " + "instantiate the model as follows: `SEWForCTC.from_pretrained(..., vocab_size=vocab_size)`. " + "or define `vocab_size` of your model's configuration." + ) + output_hidden_size = ( + config.output_hidden_size if hasattr(config, "add_adapter") and config.add_adapter else config.hidden_size + ) + self.lm_head = nn.Linear(output_hidden_size, config.vocab_size) + + # Initialize weights and apply final processing + self.post_init() + + def tie_weights(self, **kwargs): + """ + This method overwrites [`~PreTrainedModel.tie_weights`] so that adapter weights can be correctly loaded when + passing `target_lang=...` to `from_pretrained(...)`. + + This method is **not** supposed to be called by the user and is prone to be changed in the future. + """ + + if get_torch_context_manager_or_global_device() == torch.device("meta"): + return + + # Note that `tie_weights` is usually used to tie input and output embedding weights. The method is re-purposed to + # correctly load adapter layers for SEW so that we do not have to introduce a new API to + # [`PreTrainedModel`]. While slightly hacky, SEW never has to tie input and output embeddings, so that it is + # ok to repurpose this function here. + target_lang = self.target_lang + + if target_lang is not None and getattr(self.config, "adapter_attn_dim", None) is None: + raise ValueError(f"Cannot pass `target_lang`: {target_lang} if `config.adapter_attn_dim` is not defined.") + elif target_lang is None and getattr(self.config, "adapter_attn_dim", None) is not None: + logger.info("By default `target_lang` is set to 'eng'.") + elif target_lang is not None: + self.load_adapter(target_lang, force_load=True) + + def freeze_feature_encoder(self): + """ + Calling this function will disable the gradient computation for the feature encoder so that its parameter will + not be updated during training. + """ + self.sew.feature_extractor._freeze_parameters() + + def freeze_base_model(self): + """ + Calling this function will disable the gradient computation for the base model so that its parameters will not + be updated during training. Only the classification head will be updated. + """ + for param in self.sew.parameters(): + param.requires_grad = False + + @auto_docstring + def forward( + self, + input_values: torch.Tensor | None, + attention_mask: torch.Tensor | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + labels: torch.Tensor | None = None, + **kwargs, + ) -> tuple | CausalLMOutput: + r""" + labels (`torch.LongTensor` of shape `(batch_size, target_length)`, *optional*): + Labels for connectionist temporal classification. Note that `target_length` has to be smaller or equal to + the sequence length of the output logits. Indices are selected in `[-100, 0, ..., config.vocab_size - 1]`. + All labels set to `-100` are ignored (masked), the loss is only computed for labels in `[0, ..., + config.vocab_size - 1]`. + """ + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + if labels is not None and labels.max() >= self.config.vocab_size: + raise ValueError(f"Label values must be <= vocab_size: {self.config.vocab_size}") + + outputs = self.sew( + input_values, + attention_mask=attention_mask, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + + hidden_states = outputs[0] + hidden_states = self.dropout(hidden_states) + + logits = self.lm_head(hidden_states) + + loss = None + if labels is not None: + # retrieve loss input_lengths from attention_mask + attention_mask = ( + attention_mask if attention_mask is not None else torch.ones_like(input_values, dtype=torch.long) + ) + input_lengths = self._get_feat_extract_output_lengths(attention_mask.sum(-1)).to(torch.long) + + # assuming that padded tokens are filled with -100 + # when not being attended to + labels_mask = labels >= 0 + target_lengths = labels_mask.sum(-1) + flattened_targets = labels.masked_select(labels_mask) + + # ctc_loss doesn't support fp16 + log_probs = nn.functional.log_softmax(logits, dim=-1, dtype=torch.float32).transpose(0, 1) + + with torch.backends.cudnn.flags(enabled=False): + loss = nn.functional.ctc_loss( + log_probs, + flattened_targets, + input_lengths, + target_lengths, + blank=self.config.pad_token_id, + reduction=self.config.ctc_loss_reduction, + zero_infinity=self.config.ctc_zero_infinity, + ) + + if not return_dict: + output = (logits,) + outputs[_HIDDEN_STATES_START_POSITION:] + return ((loss,) + output) if loss is not None else output + + return CausalLMOutput( + loss=loss, logits=logits, hidden_states=outputs.hidden_states, attentions=outputs.attentions + ) + + +@auto_docstring( + custom_intro=""" + SEW Model with a sequence classification head on top (a linear layer over the pooled output) for tasks like + SUPERB Keyword Spotting. + """ +) +class SEWForSequenceClassification(SEWPreTrainedModel): + def __init__(self, config): + super().__init__(config) + + if hasattr(config, "add_adapter") and config.add_adapter: + raise ValueError( + "Sequence classification does not support the use of SEW adapters (config.add_adapter=True)" + ) + self.sew = SEWModel(config) + num_layers = config.num_hidden_layers + 1 # transformer layers + input embeddings + if config.use_weighted_layer_sum: + self.layer_weights = nn.Parameter(torch.ones(num_layers) / num_layers) + self.projector = nn.Linear(config.hidden_size, config.classifier_proj_size) + self.classifier = nn.Linear(config.classifier_proj_size, config.num_labels) + + # Initialize weights and apply final processing + self.post_init() + + def freeze_feature_encoder(self): + """ + Calling this function will disable the gradient computation for the feature encoder so that its parameter will + not be updated during training. + """ + self.sew.feature_extractor._freeze_parameters() + + def freeze_base_model(self): + """ + Calling this function will disable the gradient computation for the base model so that its parameters will not + be updated during training. Only the classification head will be updated. + """ + for param in self.sew.parameters(): + param.requires_grad = False + + @auto_docstring + def forward( + self, + input_values: torch.Tensor | None, + attention_mask: torch.Tensor | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + labels: torch.Tensor | None = None, + **kwargs, + ) -> tuple | SequenceClassifierOutput: + r""" + input_values (`torch.FloatTensor` of shape `(batch_size, sequence_length)`): + Float values of input raw speech waveform. Values can be obtained by loading a `.flac` or `.wav` audio file + into an array of type `list[float]`, a `numpy.ndarray` or a `torch.Tensor`, *e.g.* via the torchcodec library + (`pip install torchcodec`) or the soundfile library (`pip install soundfile`). + To prepare the array into `input_values`, the [`AutoProcessor`] should be used for padding and conversion + into a tensor of type `torch.FloatTensor`. See [`SEWProcessor.__call__`] for details. + labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*): + Labels for computing the sequence classification/regression loss. Indices should be in `[0, ..., + config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If + `config.num_labels > 1` a classification loss is computed (Cross-Entropy). + """ + + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + output_hidden_states = True if self.config.use_weighted_layer_sum else output_hidden_states + + outputs = self.sew( + input_values, + attention_mask=attention_mask, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + + if self.config.use_weighted_layer_sum: + hidden_states = outputs[_HIDDEN_STATES_START_POSITION] + hidden_states = torch.stack(hidden_states, dim=1) + norm_weights = nn.functional.softmax(self.layer_weights, dim=-1) + hidden_states = (hidden_states * norm_weights.view(-1, 1, 1)).sum(dim=1) + else: + hidden_states = outputs[0] + + hidden_states = self.projector(hidden_states) + if attention_mask is None: + pooled_output = hidden_states.mean(dim=1) + else: + padding_mask = self._get_feature_vector_attention_mask(hidden_states.shape[1], attention_mask) + expand_padding_mask = padding_mask.unsqueeze(-1).repeat(1, 1, hidden_states.shape[2]) + hidden_states[~expand_padding_mask] = 0.0 + pooled_output = hidden_states.sum(dim=1) / padding_mask.sum(dim=1).view(-1, 1) + + logits = self.classifier(pooled_output) + + loss = None + if labels is not None: + loss_fct = CrossEntropyLoss() + loss = loss_fct(logits.view(-1, self.config.num_labels), labels.view(-1)) + + if not return_dict: + output = (logits,) + outputs[_HIDDEN_STATES_START_POSITION:] + return ((loss,) + output) if loss is not None else output + + return SequenceClassifierOutput( + loss=loss, + logits=logits, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + ) + + +__all__ = ["SEWForCTC", "SEWForSequenceClassification", "SEWModel", "SEWPreTrainedModel"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sew/modular_sew.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sew/modular_sew.py new file mode 100644 index 0000000000000000000000000000000000000000..fa958f4dfe24330770dd5f4658c31115a03ed054 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sew/modular_sew.py @@ -0,0 +1,449 @@ +# Copyright 2021 ASAPP Inc. and the HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""PyTorch SEW model.""" + +import math + +import torch +from torch import nn + +from ... import initialization as init +from ...activations import ACT2FN +from ...integrations.deepspeed import is_deepspeed_zero3_enabled +from ...integrations.fsdp import is_fsdp_managed_module +from ...modeling_outputs import BaseModelOutput +from ...modeling_utils import PreTrainedModel +from ...utils import auto_docstring +from ...utils.generic import is_flash_attention_requested +from ..wav2vec2.modeling_wav2vec2 import ( + Wav2Vec2Attention, + Wav2Vec2EncoderLayer, + Wav2Vec2FeatureEncoder, + Wav2Vec2FeedForward, + Wav2Vec2ForCTC, + Wav2Vec2ForSequenceClassification, + Wav2Vec2GroupNormConvLayer, + Wav2Vec2LayerNormConvLayer, + Wav2Vec2NoLayerNormConvLayer, + Wav2Vec2SamePadLayer, + _compute_mask_indices, +) +from .configuration_sew import SEWConfig + + +_HIDDEN_STATES_START_POSITION = 1 + + +class SEWNoLayerNormConvLayer(Wav2Vec2NoLayerNormConvLayer): + pass + + +class SEWLayerNormConvLayer(Wav2Vec2LayerNormConvLayer): + pass + + +class SEWGroupNormConvLayer(Wav2Vec2GroupNormConvLayer): + pass + + +class SEWPositionalConvEmbedding(nn.Module): + def __init__(self, config): + super().__init__() + self.conv = nn.Conv1d( + config.hidden_size, + config.hidden_size, + kernel_size=config.num_conv_pos_embeddings, + padding=config.num_conv_pos_embeddings // 2, + groups=config.num_conv_pos_embedding_groups, + stride=config.squeeze_factor, + ) + + weight_norm = nn.utils.weight_norm + if hasattr(nn.utils.parametrizations, "weight_norm"): + weight_norm = nn.utils.parametrizations.weight_norm + + if is_deepspeed_zero3_enabled(): + import deepspeed + + with deepspeed.zero.GatheredParameters(self.conv.weight, modifier_rank=0): + self.conv = weight_norm(self.conv, name="weight", dim=2) + if hasattr(self.conv, "parametrizations"): + weight_g = self.conv.parametrizations.weight.original0 + weight_v = self.conv.parametrizations.weight.original1 + else: + weight_g = self.conv.weight_g + weight_v = self.conv.weight_v + deepspeed.zero.register_external_parameter(self, weight_v) + deepspeed.zero.register_external_parameter(self, weight_g) + else: + self.conv = weight_norm(self.conv, name="weight", dim=2) + + self.padding = SEWSamePadLayer(config.num_conv_pos_embeddings) + self.activation = ACT2FN[config.feat_extract_activation] + + def forward(self, hidden_states): + hidden_states = self.conv(hidden_states) + hidden_states = self.padding(hidden_states) + hidden_states = self.activation(hidden_states) + + return hidden_states + + +class SEWSamePadLayer(Wav2Vec2SamePadLayer): + pass + + +class SEWUpsampling(nn.Module): + def __init__(self, config): + super().__init__() + self.projection = nn.Linear(config.hidden_size, config.hidden_size * config.squeeze_factor) + self.activation = ACT2FN[config.feat_extract_activation] + self.squeeze_factor = config.squeeze_factor + + def forward(self, hidden_states): + hidden_states = self.projection(hidden_states) + hidden_states = self.activation(hidden_states) + + if self.squeeze_factor > 1: + # transform embedding channels to sequence length + bsz, src_len, src_embed_dim = hidden_states.size() + tgt_len = src_len * self.squeeze_factor + tgt_embed_dim = src_embed_dim // self.squeeze_factor + hidden_states = hidden_states.reshape(bsz, src_len, self.squeeze_factor, tgt_embed_dim) + hidden_states = hidden_states.reshape(bsz, tgt_len, tgt_embed_dim) + + return hidden_states + + +class SEWFeatureEncoder(Wav2Vec2FeatureEncoder): + pass + + +class SEWAttention(Wav2Vec2Attention): + pass + + +class SEWFeedForward(Wav2Vec2FeedForward): + pass + + +class SEWEncoderLayer(Wav2Vec2EncoderLayer): + pass + + +class SEWEncoder(nn.Module): + def __init__(self, config): + super().__init__() + self.config = config + self.pos_conv_embed = SEWPositionalConvEmbedding(config) + self.pool = nn.AvgPool1d(config.squeeze_factor, config.squeeze_factor) + self.layer_norm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps) + self.dropout = nn.Dropout(config.hidden_dropout) + self.layers = nn.ModuleList([SEWEncoderLayer(config) for _ in range(config.num_hidden_layers)]) + self.upsample = SEWUpsampling(config) + self.gradient_checkpointing = False + + def forward( + self, + hidden_states, + attention_mask=None, + output_attentions=False, + output_hidden_states=False, + return_dict=True, + ): + all_hidden_states = () if output_hidden_states else None + all_self_attentions = () if output_attentions else None + + if attention_mask is not None: + expand_attention_mask = attention_mask.unsqueeze(-1).repeat(1, 1, hidden_states.shape[2]) + if is_flash_attention_requested(self.config): + # make sure padded tokens output 0 + hidden_states[~expand_attention_mask] = 0.0 + # 2d mask is passed through the layers + attention_mask = attention_mask if (attention_mask is not None and 0 in attention_mask) else None + else: + # make sure padded tokens output 0 + hidden_states[~expand_attention_mask] = 0.0 + input_lengths = (attention_mask.long()).sum(-1) + # apply pooling formula to get real output_lengths + output_lengths = input_lengths // self.config.squeeze_factor + max_encoder_length = hidden_states.shape[1] // self.config.squeeze_factor + attention_ids = ( + torch.arange(0, max_encoder_length, device=output_lengths.device) + .view(1, -1) + .expand(output_lengths.shape[0], -1) + ) + attention_mask = (attention_ids < output_lengths.view(-1, 1)).long() + + # extend attention_mask + attention_mask = 1.0 - attention_mask[:, None, None, :].to(dtype=hidden_states.dtype) + attention_mask = attention_mask * torch.finfo(hidden_states.dtype).min + attention_mask = attention_mask.expand( + attention_mask.shape[0], 1, attention_mask.shape[-1], attention_mask.shape[-1] + ) + + n_input_timesteps = hidden_states.shape[1] + + hidden_states = hidden_states.transpose(1, 2) + position_embeddings = self.pos_conv_embed(hidden_states) + pooled_hidden_states = self.pool(hidden_states) + min_length = min(position_embeddings.size(-1), pooled_hidden_states.size(-1)) + hidden_states = pooled_hidden_states[..., :min_length] + position_embeddings[..., :min_length] + hidden_states = hidden_states.transpose(1, 2) + + hidden_states = self.layer_norm(hidden_states) + hidden_states = self.dropout(hidden_states) + + synced_gpus = is_deepspeed_zero3_enabled() or is_fsdp_managed_module(self) + + for layer in self.layers: + if output_hidden_states: + all_hidden_states = all_hidden_states + (hidden_states,) + + # add LayerDrop (see https://huggingface.co/papers/1909.11556 for description) + dropout_probability = torch.rand([]) + + skip_the_layer = self.training and dropout_probability < self.config.layerdrop + if not skip_the_layer or synced_gpus: + # under fsdp or deepspeed zero3 all gpus must run in sync + layer_outputs = layer( + hidden_states, attention_mask=attention_mask, output_attentions=output_attentions + ) + hidden_states = layer_outputs[0] + + if skip_the_layer: + layer_outputs = (None, None) + + if output_attentions: + all_self_attentions = all_self_attentions + (layer_outputs[1],) + + if output_hidden_states: + all_hidden_states = all_hidden_states + (hidden_states,) + + hidden_states = self.upsample(hidden_states) + if hidden_states.shape[1] < n_input_timesteps: + hidden_states = nn.functional.pad(hidden_states, (0, 0, 0, n_input_timesteps - hidden_states.shape[1])) + + if not return_dict: + return tuple(v for v in [hidden_states, all_hidden_states, all_self_attentions] if v is not None) + return BaseModelOutput( + last_hidden_state=hidden_states, + hidden_states=all_hidden_states, + attentions=all_self_attentions, + ) + + +@auto_docstring +class SEWPreTrainedModel(PreTrainedModel): + config: SEWConfig + base_model_prefix = "sew" + main_input_name = "input_values" + input_modalities = "audio" + supports_gradient_checkpointing = True + _supports_flash_attn = True + _supports_sdpa = True + _supports_flex_attn = False # needs a proper look into the mask creation + + @torch.no_grad() + def _init_weights(self, module): + """Initialize the weights""" + if isinstance(module, SEWPositionalConvEmbedding): + init.normal_( + module.conv.weight, + mean=0, + std=2 * math.sqrt(1 / (module.conv.kernel_size[0] * module.conv.in_channels)), + ) + init.constant_(module.conv.bias, 0) + elif isinstance(module, nn.Linear): + init.normal_(module.weight, mean=0.0, std=self.config.initializer_range) + elif isinstance(module, (nn.LayerNorm, nn.GroupNorm)): + init.zeros_(module.bias) + init.ones_(module.weight) + elif isinstance(module, nn.Conv1d): + if is_deepspeed_zero3_enabled(): + import deepspeed + + if hasattr(module, "weight_v") and hasattr(module, "weight_g"): + with deepspeed.zero.GatheredParameters([module.weight_v, module.weight_g], modifier_rank=0): + init.kaiming_normal_(module.weight) + else: + with deepspeed.zero.GatheredParameters(module.weight, modifier_rank=0): + init.kaiming_normal_(module.weight) + else: + init.kaiming_normal_(module.weight) + + if isinstance(module, (nn.Linear, nn.Conv1d)) and module.bias is not None: + init.zeros_(module.bias) + + def _get_feat_extract_output_lengths(self, input_lengths: torch.LongTensor | int): + """ + Computes the output length of the convolutional layers + """ + + def _conv_out_length(input_length, kernel_size, stride): + # 1D convolutional layer output length formula taken + # from https://pytorch.org/docs/stable/generated/torch.nn.Conv1d.html + return torch.div(input_length - kernel_size, stride, rounding_mode="floor") + 1 + + for kernel_size, stride in zip(self.config.conv_kernel, self.config.conv_stride): + input_lengths = _conv_out_length(input_lengths, kernel_size, stride) + + return input_lengths + + def _get_feature_vector_attention_mask(self, feature_vector_length: int, attention_mask: torch.LongTensor): + output_lengths = self._get_feat_extract_output_lengths(attention_mask.sum(-1)).to(torch.long) + batch_size = attention_mask.shape[0] + + attention_mask = torch.zeros( + (batch_size, feature_vector_length), dtype=attention_mask.dtype, device=attention_mask.device + ) + # these two operations makes sure that all values before the output lengths idxs are attended to + attention_mask[(torch.arange(attention_mask.shape[0], device=attention_mask.device), output_lengths - 1)] = 1 + attention_mask = attention_mask.flip([-1]).cumsum(-1).flip([-1]).bool() + return attention_mask + + +@auto_docstring +class SEWModel(SEWPreTrainedModel): + def __init__(self, config: SEWConfig): + super().__init__(config) + self.config = config + self.feature_extractor = SEWFeatureEncoder(config) + self.layer_norm = nn.LayerNorm(config.conv_dim[-1], eps=config.layer_norm_eps) + + self.project_features = config.conv_dim[-1] != config.hidden_size + if self.project_features: + self.feature_projection = nn.Linear(config.conv_dim[-1], config.hidden_size) + self.feature_dropout = nn.Dropout(config.feat_proj_dropout) + + if config.mask_time_prob > 0.0 or config.mask_feature_prob > 0.0: + self.masked_spec_embed = nn.Parameter(torch.Tensor(config.hidden_size).uniform_()) + + self.encoder = SEWEncoder(config) + + # Initialize weights and apply final processing + self.post_init() + + # Copied from transformers.models.wav2vec2.modeling_wav2vec2.Wav2Vec2Model._mask_hidden_states + def _mask_hidden_states( + self, + hidden_states: torch.FloatTensor, + mask_time_indices: torch.FloatTensor | None = None, + attention_mask: torch.LongTensor | None = None, + ): + """ + Masks extracted features along time axis and/or along feature axis according to + [SpecAugment](https://huggingface.co/papers/1904.08779). + """ + + # `config.apply_spec_augment` can set masking to False + if not getattr(self.config, "apply_spec_augment", True): + return hidden_states + + # generate indices & apply SpecAugment along time axis + batch_size, sequence_length, hidden_size = hidden_states.size() + + if mask_time_indices is not None: + # apply SpecAugment along time axis with given mask_time_indices + hidden_states[mask_time_indices] = self.masked_spec_embed.to(hidden_states.dtype) + elif self.config.mask_time_prob > 0 and self.training: + mask_time_indices = _compute_mask_indices( + (batch_size, sequence_length), + mask_prob=self.config.mask_time_prob, + mask_length=self.config.mask_time_length, + attention_mask=attention_mask, + min_masks=self.config.mask_time_min_masks, + ) + mask_time_indices = torch.tensor(mask_time_indices, device=hidden_states.device, dtype=torch.bool) + hidden_states[mask_time_indices] = self.masked_spec_embed.to(hidden_states.dtype) + + if self.config.mask_feature_prob > 0 and self.training: + # generate indices & apply SpecAugment along feature axis + mask_feature_indices = _compute_mask_indices( + (batch_size, hidden_size), + mask_prob=self.config.mask_feature_prob, + mask_length=self.config.mask_feature_length, + min_masks=self.config.mask_feature_min_masks, + ) + mask_feature_indices = torch.tensor(mask_feature_indices, device=hidden_states.device, dtype=torch.bool) + mask_feature_indices = mask_feature_indices[:, None].expand(-1, sequence_length, -1) + hidden_states[mask_feature_indices] = 0 + + return hidden_states + + @auto_docstring + def forward( + self, + input_values: torch.Tensor | None, + attention_mask: torch.Tensor | None = None, + mask_time_indices: torch.FloatTensor | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + **kwargs, + ) -> tuple | BaseModelOutput: + r""" + mask_time_indices (`torch.BoolTensor` of shape `(batch_size, sequence_length)`, *optional*): + Indices to mask extracted features for contrastive loss. When in training mode, model learns to predict + masked extracted features in *config.proj_codevector_dim* space. + """ + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + extract_features = self.feature_extractor(input_values) + extract_features = extract_features.transpose(1, 2) + extract_features = self.layer_norm(extract_features) + + if self.project_features: + extract_features = self.feature_projection(extract_features) + hidden_states = self.feature_dropout(extract_features) + + if attention_mask is not None: + # compute reduced attention_mask corresponding to feature vectors + attention_mask = self._get_feature_vector_attention_mask(hidden_states.shape[1], attention_mask) + + hidden_states = self._mask_hidden_states(hidden_states, mask_time_indices=mask_time_indices) + + encoder_outputs = self.encoder( + hidden_states, + attention_mask=attention_mask, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + + hidden_states = encoder_outputs[0] + + if not return_dict: + return (hidden_states,) + encoder_outputs[1:] + + return BaseModelOutput( + last_hidden_state=hidden_states, + hidden_states=encoder_outputs.hidden_states, + attentions=encoder_outputs.attentions, + ) + + +class SEWForCTC(Wav2Vec2ForCTC): + pass + + +class SEWForSequenceClassification(Wav2Vec2ForSequenceClassification): + pass + + +__all__ = ["SEWForCTC", "SEWForSequenceClassification", "SEWModel", "SEWPreTrainedModel"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sew_d/__init__.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sew_d/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..7902aa464a9cfd5b465c2448014e218f4540c9d3 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sew_d/__init__.py @@ -0,0 +1,27 @@ +# Copyright 2024 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from typing import TYPE_CHECKING + +from ...utils import _LazyModule +from ...utils.import_utils import define_import_structure + + +if TYPE_CHECKING: + from .configuration_sew_d import * + from .modeling_sew_d import * +else: + import sys + + _file = globals()["__file__"] + sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__) diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sew_d/configuration_sew_d.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sew_d/configuration_sew_d.py new file mode 100644 index 0000000000000000000000000000000000000000..392c4d3c4289281249b7d898b4695a4cce4a88ba --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sew_d/configuration_sew_d.py @@ -0,0 +1,293 @@ +# Copyright 2021 ASAPP Inc. and The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""SEW-D model configuration""" + +import functools +import operator + +from ...configuration_utils import PreTrainedConfig +from ...utils import logging + + +logger = logging.get_logger(__name__) + + +class SEWDConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`SEWDModel`]. It is used to instantiate a SEW-D + model according to the specified arguments, defining the model architecture. Instantiating a configuration with the + defaults will yield a similar configuration to that of the SEW-D + [asapp/sew-d-tiny-100k](https://huggingface.co/asapp/sew-d-tiny-100k) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + + Args: + vocab_size (`int`, *optional*, defaults to 32): + Vocabulary size of the SEW-D model. Defines the number of different tokens that can be represented by the + `inputs_ids` passed when calling [`SEWD`]. + hidden_size (`int`, *optional*, defaults to 768): + Dimensionality of the encoder layers and the pooler layer. + num_hidden_layers (`int`, *optional*, defaults to 12): + Number of hidden layers in the Transformer encoder. + num_attention_heads (`int`, *optional*, defaults to 12): + Number of attention heads for each attention layer in the Transformer encoder. + intermediate_size (`int`, *optional*, defaults to 3072): + Dimensionality of the "intermediate" (i.e., feed-forward) layer in the Transformer encoder. + squeeze_factor (`int`, *optional*, defaults to 2): + Sequence length downsampling factor after the encoder and upsampling factor after the transformer. + max_position_embeddings (`int`, *optional*, defaults to 512): + The maximum sequence length that this model might ever be used with. Typically set this to something large + just in case (e.g., 512 or 1024 or 2048). + position_buckets (`int`, *optional*, defaults to 256): + The maximum size of relative position embeddings. + share_att_key (`bool`, *optional*, defaults to `True`): + Whether to share attention key with c2p and p2c. + relative_attention (`bool`, *optional*, defaults to `True`): + Whether to use relative position encoding. + pos_att_type (`tuple[str]`, *optional*, defaults to `("p2c", "c2p")`): + The type of relative position attention, it can be a combination of `("p2c", "c2p")`, e.g. `("p2c")`, + `("p2c", "c2p")`, `("p2c", "c2p")`. + norm_rel_ebd (`str`, *optional*, defaults to `"layer_norm"`): + Whether to use layer norm in relative embedding (`"layer_norm"` if yes) + hidden_act (`str` or `function`, *optional*, defaults to `"gelu_python"`): + The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`, + `"relu"`, `"selu"`, `"gelu_python"` and `"gelu_new"` are supported. + hidden_dropout (`float`, *optional*, defaults to 0.1): + Deprecated. Not used by the model and will be removed in a future version. + activation_dropout (`float`, *optional*, defaults to 0.1): + The dropout probability for all fully connected layers in the embeddings, encoder, and pooler. + attention_dropout (`float`, *optional*, defaults to 0.1): + The dropout ratio for the attention probabilities. + final_dropout (`float`, *optional*, defaults to 0.1): + The dropout probability for the final projection layer of [`SEWDForCTC`]. + initializer_range (`float`, *optional*, defaults to 0.02): + The standard deviation of the truncated_normal_initializer for initializing all weight matrices. + layer_norm_eps (`float`, *optional*, defaults to 1e-7): + The epsilon used by the layer normalization layers in the transformer encoder. + feature_layer_norm_eps (`float`, *optional*, defaults to 1e-5): + The epsilon used by the layer normalization after the feature encoder. + feat_extract_norm (`str`, *optional*, defaults to `"group"`): + The norm to be applied to 1D convolutional layers in feature encoder. One of `"group"` for group + normalization of only the first 1D convolutional layer or `"layer"` for layer normalization of all 1D + convolutional layers. + feat_proj_dropout (`float`, *optional*, defaults to 0.0): + The dropout probability for output of the feature encoder. + feat_extract_activation (`str, `optional`, defaults to `"gelu"`): + The non-linear activation function (function or string) in the 1D convolutional layers of the feature + extractor. If string, `"gelu"`, `"relu"`, `"selu"` and `"gelu_new"` are supported. + conv_dim (`tuple[int]` or `list[int]`, *optional*, defaults to `(64, 128, 128, 128, 128, 256, 256, 256, 256, 512, 512, 512, 512)`): + A tuple of integers defining the number of input and output channels of each 1D convolutional layer in the + feature encoder. The length of *conv_dim* defines the number of 1D convolutional layers. + conv_stride (`tuple[int]` or `list[int]`, *optional*, defaults to `(5, 2, 1, 2, 1, 2, 1, 2, 1, 2, 1, 2, 1)`): + A tuple of integers defining the stride of each 1D convolutional layer in the feature encoder. The length + of *conv_stride* defines the number of convolutional layers and has to match the length of *conv_dim*. + conv_kernel (`tuple[int]` or `list[int]`, *optional*, defaults to `(10, 3, 1, 3, 1, 3, 1, 3, 1, 2, 1, 2, 1)`): + A tuple of integers defining the kernel size of each 1D convolutional layer in the feature encoder. The + length of *conv_kernel* defines the number of convolutional layers and has to match the length of + *conv_dim*. + conv_bias (`bool`, *optional*, defaults to `False`): + Whether the 1D convolutional layers have a bias. + num_conv_pos_embeddings (`int`, *optional*, defaults to 128): + Number of convolutional positional embeddings. Defines the kernel size of 1D convolutional positional + embeddings layer. + num_conv_pos_embedding_groups (`int`, *optional*, defaults to 16): + Number of groups of 1D convolutional positional embeddings layer. + apply_spec_augment (`bool`, *optional*, defaults to `True`): + Whether to apply *SpecAugment* data augmentation to the outputs of the feature encoder. For reference see + [SpecAugment: A Simple Data Augmentation Method for Automatic Speech + Recognition](https://huggingface.co/papers/1904.08779). + mask_time_prob (`float`, *optional*, defaults to 0.05): + Percentage (between 0 and 1) of all feature vectors along the time axis which will be masked. The masking + procedure generates ''mask_time_prob*len(time_axis)/mask_time_length'' independent masks over the axis. If + reasoning from the probability of each feature vector to be chosen as the start of the vector span to be + masked, *mask_time_prob* should be `prob_vector_start*mask_time_length`. Note that overlap may decrease the + actual percentage of masked vectors. This is only relevant if `apply_spec_augment is True`. + mask_time_length (`int`, *optional*, defaults to 10): + Length of vector span along the time axis. + mask_time_min_masks (`int`, *optional*, defaults to 2),: + The minimum number of masks of length `mask_feature_length` generated along the time axis, each time step, + irrespectively of `mask_feature_prob`. Only relevant if ''mask_time_prob*len(time_axis)/mask_time_length < + mask_time_min_masks'' + mask_feature_prob (`float`, *optional*, defaults to 0.0): + Percentage (between 0 and 1) of all feature vectors along the feature axis which will be masked. The + masking procedure generates ''mask_feature_prob*len(feature_axis)/mask_time_length'' independent masks over + the axis. If reasoning from the probability of each feature vector to be chosen as the start of the vector + span to be masked, *mask_feature_prob* should be `prob_vector_start*mask_feature_length`. Note that overlap + may decrease the actual percentage of masked vectors. This is only relevant if `apply_spec_augment is + True`. + mask_feature_length (`int`, *optional*, defaults to 10): + Length of vector span along the feature axis. + mask_feature_min_masks (`int`, *optional*, defaults to 0),: + The minimum number of masks of length `mask_feature_length` generated along the feature axis, each time + step, irrespectively of `mask_feature_prob`. Only relevant if + ''mask_feature_prob*len(feature_axis)/mask_feature_length < mask_feature_min_masks'' + diversity_loss_weight (`int`, *optional*, defaults to 0.1): + The weight of the codebook diversity loss component. + ctc_loss_reduction (`str`, *optional*, defaults to `"sum"`): + Specifies the reduction to apply to the output of `torch.nn.CTCLoss`. Only relevant when training an + instance of [`SEWDForCTC`]. + ctc_zero_infinity (`bool`, *optional*, defaults to `False`): + Whether to zero infinite losses and the associated gradients of `torch.nn.CTCLoss`. Infinite losses mainly + occur when the inputs are too short to be aligned to the targets. Only relevant when training an instance + of [`SEWDForCTC`]. + use_weighted_layer_sum (`bool`, *optional*, defaults to `False`): + Whether to use a weighted average of layer outputs with learned weights. Only relevant when using an + instance of [`Wav2Vec2ForSequenceClassification`]. + classifier_proj_size (`int`, *optional*, defaults to 256): + Dimensionality of the projection before token mean-pooling for classification. + + Example: + + ```python + >>> from transformers import SEWDConfig, SEWDModel + + >>> # Initializing a SEW-D asapp/sew-d-tiny-100k style configuration + >>> configuration = SEWDConfig() + + >>> # Initializing a model (with random weights) from the asapp/sew-d-tiny-100k style configuration + >>> model = SEWDModel(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "sew-d" + + def __init__( + self, + vocab_size=32, + hidden_size=768, + num_hidden_layers=12, + num_attention_heads=12, + intermediate_size=3072, + squeeze_factor=2, + max_position_embeddings=512, + position_buckets=256, + share_att_key=True, + relative_attention=True, + pos_att_type=("p2c", "c2p"), + norm_rel_ebd="layer_norm", + hidden_act="gelu_python", + hidden_dropout=0.1, + activation_dropout=0.1, + attention_dropout=0.1, + feat_proj_dropout=0.0, + final_dropout=0.1, + initializer_range=0.02, + layer_norm_eps=1e-7, + feature_layer_norm_eps=1e-5, + feat_extract_norm="group", + feat_extract_activation="gelu", + conv_dim=(64, 128, 128, 128, 128, 256, 256, 256, 256, 512, 512, 512, 512), + conv_stride=(5, 2, 1, 2, 1, 2, 1, 2, 1, 2, 1, 2, 1), + conv_kernel=(10, 3, 1, 3, 1, 3, 1, 3, 1, 2, 1, 2, 1), + conv_bias=False, + num_conv_pos_embeddings=128, + num_conv_pos_embedding_groups=16, + apply_spec_augment=True, + mask_time_prob=0.05, + mask_time_length=10, + mask_time_min_masks=2, + mask_feature_prob=0.0, + mask_feature_length=10, + mask_feature_min_masks=0, + ctc_loss_reduction="mean", + ctc_zero_infinity=False, + use_weighted_layer_sum=False, + classifier_proj_size=256, + pad_token_id=0, + bos_token_id=1, + eos_token_id=2, + **kwargs, + ): + super().__init__(**kwargs) + self.pad_token_id = pad_token_id + self.bos_token_id = bos_token_id + self.eos_token_id = eos_token_id + self.hidden_size = hidden_size + self.feat_extract_norm = feat_extract_norm + self.feat_extract_activation = feat_extract_activation + self.conv_dim = list(conv_dim) + self.conv_stride = list(conv_stride) + self.conv_kernel = list(conv_kernel) + self.conv_bias = conv_bias + self.num_conv_pos_embeddings = num_conv_pos_embeddings + self.num_conv_pos_embedding_groups = num_conv_pos_embedding_groups + self.num_feat_extract_layers = len(self.conv_dim) + self.num_hidden_layers = num_hidden_layers + self.intermediate_size = intermediate_size + self.squeeze_factor = squeeze_factor + self.max_position_embeddings = max_position_embeddings + self.position_buckets = position_buckets + self.share_att_key = share_att_key + self.relative_attention = relative_attention + self.norm_rel_ebd = norm_rel_ebd + self.pos_att_type = list(pos_att_type) + self.hidden_act = hidden_act + self.num_attention_heads = num_attention_heads + self._hidden_dropout = hidden_dropout + self.attention_dropout = attention_dropout + self.activation_dropout = activation_dropout + self.feat_proj_dropout = feat_proj_dropout + self.final_dropout = final_dropout + self.layer_norm_eps = layer_norm_eps + self.feature_layer_norm_eps = feature_layer_norm_eps + self.initializer_range = initializer_range + self.vocab_size = vocab_size + + if ( + (len(self.conv_stride) != self.num_feat_extract_layers) + or (len(self.conv_kernel) != self.num_feat_extract_layers) + or (len(self.conv_dim) != self.num_feat_extract_layers) + ): + raise ValueError( + "Configuration for convolutional layers is incorrect. " + "It is required that `len(config.conv_dim)` == `len(config.conv_stride)` == `len(config.conv_kernel)`, " + f"but is `len(config.conv_dim) = {len(self.conv_dim)}`, `len(config.conv_stride) " + f"= {len(self.conv_stride)}`, `len(config.conv_kernel) = {len(self.conv_kernel)}`." + ) + + # fine-tuning config parameters for SpecAugment: https://huggingface.co/papers/1904.08779 + self.apply_spec_augment = apply_spec_augment + self.mask_time_prob = mask_time_prob + self.mask_time_length = mask_time_length + self.mask_time_min_masks = mask_time_min_masks + self.mask_feature_prob = mask_feature_prob + self.mask_feature_length = mask_feature_length + self.mask_feature_min_masks = mask_feature_min_masks + + # ctc loss + self.ctc_loss_reduction = ctc_loss_reduction + self.ctc_zero_infinity = ctc_zero_infinity + + # sequence classification + self.use_weighted_layer_sum = use_weighted_layer_sum + self.classifier_proj_size = classifier_proj_size + + @property + def inputs_to_logits_ratio(self): + return functools.reduce(operator.mul, self.conv_stride, 1) + + def to_dict(self): + """ + Serializes this instance to a Python dictionary. + """ + output = super().to_dict() + output["hidden_dropout"] = output.pop("_hidden_dropout") + return output + + +__all__ = ["SEWDConfig"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sew_d/modeling_sew_d.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sew_d/modeling_sew_d.py new file mode 100644 index 0000000000000000000000000000000000000000..7e3872b68978a4369f316ef5940476fc145fcefb --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/sew_d/modeling_sew_d.py @@ -0,0 +1,1624 @@ +# Copyright 2021 ASAPP Inc. and the HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""PyTorch SEW model.""" + +import math +from collections.abc import Sequence + +import numpy as np +import torch +from torch import nn +from torch.nn import CrossEntropyLoss, LayerNorm + +from ... import initialization as init +from ...activations import ACT2FN +from ...integrations.deepspeed import is_deepspeed_zero3_enabled +from ...modeling_layers import GradientCheckpointingLayer +from ...modeling_outputs import BaseModelOutput, CausalLMOutput, SequenceClassifierOutput +from ...modeling_utils import PreTrainedModel, get_torch_context_manager_or_global_device +from ...utils import auto_docstring, logging +from .configuration_sew_d import SEWDConfig + + +logger = logging.get_logger(__name__) + +_HIDDEN_STATES_START_POSITION = 1 + + +# Copied from transformers.models.wav2vec2.modeling_wav2vec2._compute_mask_indices +def _compute_mask_indices( + shape: tuple[int, int], + mask_prob: float, + mask_length: int, + attention_mask: torch.LongTensor | None = None, + min_masks: int = 0, +) -> np.ndarray: + """ + Computes random mask spans for a given shape. Used to implement [SpecAugment: A Simple Data Augmentation Method for + ASR](https://huggingface.co/papers/1904.08779). Note that this method is not optimized to run on TPU and should be run on + CPU as part of the preprocessing during training. + + Args: + shape: The shape for which to compute masks. This should be of a tuple of size 2 where + the first element is the batch size and the second element is the length of the axis to span. + mask_prob: The percentage of the whole axis (between 0 and 1) which will be masked. The number of + independently generated mask spans of length `mask_length` is computed by + `mask_prob*shape[1]/mask_length`. Note that due to overlaps, `mask_prob` is an upper bound and the + actual percentage will be smaller. + mask_length: size of the mask + min_masks: minimum number of masked spans + attention_mask: A (right-padded) attention mask which independently shortens the feature axis of + each batch dimension. + """ + batch_size, sequence_length = shape + + if mask_length < 1: + raise ValueError("`mask_length` has to be bigger than 0.") + + if mask_length > sequence_length: + raise ValueError( + f"`mask_length` has to be smaller than `sequence_length`, but got `mask_length`: {mask_length}" + f" and `sequence_length`: {sequence_length}`" + ) + + # epsilon is used for probabilistic rounding + epsilon = np.random.rand(1).item() + + def compute_num_masked_span(input_length): + """Given input length, compute how many spans should be masked""" + num_masked_span = int(mask_prob * input_length / mask_length + epsilon) + num_masked_span = max(num_masked_span, min_masks) + + # make sure num masked span <= sequence_length + if num_masked_span * mask_length > sequence_length: + num_masked_span = sequence_length // mask_length + + # make sure num_masked span is also <= input_length - (mask_length - 1) + if input_length - (mask_length - 1) < num_masked_span: + num_masked_span = max(input_length - (mask_length - 1), 0) + + return num_masked_span + + # compute number of masked spans in batch + input_lengths = ( + attention_mask.detach().sum(-1).tolist() + if attention_mask is not None + else [sequence_length for _ in range(batch_size)] + ) + + # SpecAugment mask to fill + spec_aug_mask = np.zeros((batch_size, sequence_length), dtype=bool) + spec_aug_mask_idxs = [] + + max_num_masked_span = compute_num_masked_span(sequence_length) + + if max_num_masked_span == 0: + return spec_aug_mask + + for input_length in input_lengths: + # compute num of masked spans for this input + num_masked_span = compute_num_masked_span(input_length) + + # get random indices to mask + spec_aug_mask_idx = np.random.choice( + np.arange(input_length - (mask_length - 1)), num_masked_span, replace=False + ) + + # pick first sampled index that will serve as a dummy index to pad vector + # to ensure same dimension for all batches due to probabilistic rounding + # Picking first sample just pads those vectors twice. + if len(spec_aug_mask_idx) == 0: + # this case can only happen if `input_length` is strictly smaller then + # `sequence_length` in which case the last token has to be a padding + # token which we can use as a dummy mask id + dummy_mask_idx = sequence_length - 1 + else: + dummy_mask_idx = spec_aug_mask_idx[0] + + spec_aug_mask_idx = np.concatenate( + [spec_aug_mask_idx, np.ones(max_num_masked_span - num_masked_span, dtype=np.int32) * dummy_mask_idx] + ) + spec_aug_mask_idxs.append(spec_aug_mask_idx) + + spec_aug_mask_idxs = np.array(spec_aug_mask_idxs) + + # expand masked indices to masked spans + spec_aug_mask_idxs = np.broadcast_to( + spec_aug_mask_idxs[:, :, None], (batch_size, max_num_masked_span, mask_length) + ) + spec_aug_mask_idxs = spec_aug_mask_idxs.reshape(batch_size, max_num_masked_span * mask_length) + + # add offset to the starting indexes so that indexes now create a span + offsets = np.arange(mask_length)[None, None, :] + offsets = np.broadcast_to(offsets, (batch_size, max_num_masked_span, mask_length)).reshape( + batch_size, max_num_masked_span * mask_length + ) + spec_aug_mask_idxs = spec_aug_mask_idxs + offsets + + # ensure that we cannot have indices larger than sequence_length + if spec_aug_mask_idxs.max() > sequence_length - 1: + spec_aug_mask_idxs[spec_aug_mask_idxs > sequence_length - 1] = sequence_length - 1 + + # scatter indices to mask + np.put_along_axis(spec_aug_mask, spec_aug_mask_idxs, 1, -1) + + return spec_aug_mask + + +def make_log_bucket_position(relative_pos, bucket_size, max_position): + sign = torch.sign(relative_pos) + mid = bucket_size // 2 + abs_pos = torch.where( + (relative_pos < mid) & (relative_pos > -mid), + torch.tensor(mid - 1).type_as(relative_pos), + torch.abs(relative_pos), + ) + log_pos = ( + torch.ceil(torch.log(abs_pos / mid) / torch.log(torch.tensor((max_position - 1) / mid)) * (mid - 1)) + mid + ) + bucket_pos = torch.where(abs_pos <= mid, relative_pos.type_as(log_pos), log_pos * sign) + return bucket_pos + + +def build_relative_position(query_size, key_size, bucket_size=-1, max_position=-1, device=None): + """ + Build relative position according to the query and key + + We assume the absolute position of query \\(P_q\\) is range from (0, query_size) and the absolute position of key + \\(P_k\\) is range from (0, key_size), The relative positions from query to key is \\(R_{q \\rightarrow k} = P_q - + P_k\\) + + Args: + query_size (int): the length of query + key_size (int): the length of key + bucket_size (int): the size of position bucket + max_position (int): the maximum allowed absolute position + device (`torch.device`): the device on which tensors will be created. + + Return: + `torch.LongTensor`: A tensor with shape [1, query_size, key_size] + """ + + q_ids = torch.arange(0, query_size, device=device) + k_ids = torch.arange(0, key_size, device=device) + rel_pos_ids = q_ids[:, None] - k_ids[None, :] + if bucket_size > 0 and max_position > 0: + rel_pos_ids = make_log_bucket_position(rel_pos_ids, bucket_size, max_position) + rel_pos_ids = rel_pos_ids.to(torch.long) + rel_pos_ids = rel_pos_ids[:query_size, :] + rel_pos_ids = rel_pos_ids.unsqueeze(0) + return rel_pos_ids + + +@torch.jit.script +# Copied from transformers.models.deberta.modeling_deberta.c2p_dynamic_expand +def c2p_dynamic_expand(c2p_pos, query_layer, relative_pos): + return c2p_pos.expand([query_layer.size(0), query_layer.size(1), query_layer.size(2), relative_pos.size(-1)]) + + +@torch.jit.script +# Copied from transformers.models.deberta.modeling_deberta.p2c_dynamic_expand +def p2c_dynamic_expand(c2p_pos, query_layer, key_layer): + return c2p_pos.expand([query_layer.size(0), query_layer.size(1), key_layer.size(-2), key_layer.size(-2)]) + + +@torch.jit.script +# Copied from transformers.models.deberta.modeling_deberta.pos_dynamic_expand +def pos_dynamic_expand(pos_index, p2c_att, key_layer): + return pos_index.expand(p2c_att.size()[:2] + (pos_index.size(-2), key_layer.size(-2))) + + +def get_mask(input, local_context): + if not isinstance(local_context, DropoutContext): + dropout = local_context + mask = None + else: + dropout = local_context.dropout + dropout *= local_context.scale + mask = local_context.mask if local_context.reuse_mask else None + + if dropout > 0 and mask is None: + mask = (1 - torch.empty_like(input).bernoulli_(1 - dropout)).to(torch.bool) + + if isinstance(local_context, DropoutContext): + if local_context.mask is None: + local_context.mask = mask + + return mask, dropout + + +# Copied from transformers.models.wav2vec2.modeling_wav2vec2.Wav2Vec2NoLayerNormConvLayer with Wav2Vec2->SEWD +class SEWDNoLayerNormConvLayer(GradientCheckpointingLayer): + def __init__(self, config, layer_id=0): + super().__init__() + self.in_conv_dim = config.conv_dim[layer_id - 1] if layer_id > 0 else 1 + self.out_conv_dim = config.conv_dim[layer_id] + + self.conv = nn.Conv1d( + self.in_conv_dim, + self.out_conv_dim, + kernel_size=config.conv_kernel[layer_id], + stride=config.conv_stride[layer_id], + bias=config.conv_bias, + ) + self.activation = ACT2FN[config.feat_extract_activation] + + def forward(self, hidden_states): + hidden_states = self.conv(hidden_states) + hidden_states = self.activation(hidden_states) + return hidden_states + + +# Copied from transformers.models.wav2vec2.modeling_wav2vec2.Wav2Vec2LayerNormConvLayer with Wav2Vec2->SEWD +class SEWDLayerNormConvLayer(GradientCheckpointingLayer): + def __init__(self, config, layer_id=0): + super().__init__() + self.in_conv_dim = config.conv_dim[layer_id - 1] if layer_id > 0 else 1 + self.out_conv_dim = config.conv_dim[layer_id] + + self.conv = nn.Conv1d( + self.in_conv_dim, + self.out_conv_dim, + kernel_size=config.conv_kernel[layer_id], + stride=config.conv_stride[layer_id], + bias=config.conv_bias, + ) + self.layer_norm = nn.LayerNorm(self.out_conv_dim, elementwise_affine=True) + self.activation = ACT2FN[config.feat_extract_activation] + + def forward(self, hidden_states): + hidden_states = self.conv(hidden_states) + + hidden_states = hidden_states.transpose(-2, -1) + hidden_states = self.layer_norm(hidden_states) + hidden_states = hidden_states.transpose(-2, -1) + + hidden_states = self.activation(hidden_states) + return hidden_states + + +# Copied from transformers.models.wav2vec2.modeling_wav2vec2.Wav2Vec2GroupNormConvLayer with Wav2Vec2->SEWD +class SEWDGroupNormConvLayer(GradientCheckpointingLayer): + def __init__(self, config, layer_id=0): + super().__init__() + self.in_conv_dim = config.conv_dim[layer_id - 1] if layer_id > 0 else 1 + self.out_conv_dim = config.conv_dim[layer_id] + + self.conv = nn.Conv1d( + self.in_conv_dim, + self.out_conv_dim, + kernel_size=config.conv_kernel[layer_id], + stride=config.conv_stride[layer_id], + bias=config.conv_bias, + ) + self.activation = ACT2FN[config.feat_extract_activation] + + self.layer_norm = nn.GroupNorm(num_groups=self.out_conv_dim, num_channels=self.out_conv_dim, affine=True) + + def forward(self, hidden_states): + hidden_states = self.conv(hidden_states) + hidden_states = self.layer_norm(hidden_states) + hidden_states = self.activation(hidden_states) + return hidden_states + + +# Copied from transformers.models.sew.modeling_sew.SEWPositionalConvEmbedding with SEW->SEWD +class SEWDPositionalConvEmbedding(nn.Module): + def __init__(self, config): + super().__init__() + self.conv = nn.Conv1d( + config.hidden_size, + config.hidden_size, + kernel_size=config.num_conv_pos_embeddings, + padding=config.num_conv_pos_embeddings // 2, + groups=config.num_conv_pos_embedding_groups, + stride=config.squeeze_factor, + ) + + weight_norm = nn.utils.weight_norm + if hasattr(nn.utils.parametrizations, "weight_norm"): + weight_norm = nn.utils.parametrizations.weight_norm + + if is_deepspeed_zero3_enabled(): + import deepspeed + + with deepspeed.zero.GatheredParameters(self.conv.weight, modifier_rank=0): + self.conv = weight_norm(self.conv, name="weight", dim=2) + if hasattr(self.conv, "parametrizations"): + weight_g = self.conv.parametrizations.weight.original0 + weight_v = self.conv.parametrizations.weight.original1 + else: + weight_g = self.conv.weight_g + weight_v = self.conv.weight_v + deepspeed.zero.register_external_parameter(self, weight_v) + deepspeed.zero.register_external_parameter(self, weight_g) + else: + self.conv = weight_norm(self.conv, name="weight", dim=2) + + self.padding = SEWDSamePadLayer(config.num_conv_pos_embeddings) + self.activation = ACT2FN[config.feat_extract_activation] + + def forward(self, hidden_states): + hidden_states = self.conv(hidden_states) + hidden_states = self.padding(hidden_states) + hidden_states = self.activation(hidden_states) + + return hidden_states + + +# Copied from transformers.models.wav2vec2.modeling_wav2vec2.Wav2Vec2SamePadLayer with Wav2Vec2->SEW +class SEWDSamePadLayer(nn.Module): + def __init__(self, num_conv_pos_embeddings): + super().__init__() + self.num_pad_remove = 1 if num_conv_pos_embeddings % 2 == 0 else 0 + + def forward(self, hidden_states): + if self.num_pad_remove > 0: + hidden_states = hidden_states[:, :, : -self.num_pad_remove] + return hidden_states + + +# Copied from transformers.models.sew.modeling_sew.SEWUpsampling with SEW->SEWD +class SEWDUpsampling(nn.Module): + def __init__(self, config): + super().__init__() + self.projection = nn.Linear(config.hidden_size, config.hidden_size * config.squeeze_factor) + self.activation = ACT2FN[config.feat_extract_activation] + self.squeeze_factor = config.squeeze_factor + + def forward(self, hidden_states): + hidden_states = self.projection(hidden_states) + hidden_states = self.activation(hidden_states) + + if self.squeeze_factor > 1: + # transform embedding channels to sequence length + bsz, src_len, src_embed_dim = hidden_states.size() + tgt_len = src_len * self.squeeze_factor + tgt_embed_dim = src_embed_dim // self.squeeze_factor + hidden_states = hidden_states.reshape(bsz, src_len, self.squeeze_factor, tgt_embed_dim) + hidden_states = hidden_states.reshape(bsz, tgt_len, tgt_embed_dim) + + return hidden_states + + +# Copied from transformers.models.wav2vec2.modeling_wav2vec2.Wav2Vec2FeatureEncoder with Wav2Vec2->SEWD +class SEWDFeatureEncoder(nn.Module): + """Construct the features from raw audio waveform""" + + def __init__(self, config): + super().__init__() + + if config.feat_extract_norm == "group": + conv_layers = [SEWDGroupNormConvLayer(config, layer_id=0)] + [ + SEWDNoLayerNormConvLayer(config, layer_id=i + 1) for i in range(config.num_feat_extract_layers - 1) + ] + elif config.feat_extract_norm == "layer": + conv_layers = [SEWDLayerNormConvLayer(config, layer_id=i) for i in range(config.num_feat_extract_layers)] + else: + raise ValueError( + f"`config.feat_extract_norm` is {config.feat_extract_norm}, but has to be one of ['group', 'layer']" + ) + self.conv_layers = nn.ModuleList(conv_layers) + self.gradient_checkpointing = False + self._requires_grad = True + + def _freeze_parameters(self): + for param in self.parameters(): + param.requires_grad = False + self._requires_grad = False + + def forward(self, input_values): + hidden_states = input_values[:, None] + + # make sure hidden_states require grad for gradient_checkpointing + if self._requires_grad and self.training: + hidden_states.requires_grad = True + + for conv_layer in self.conv_layers: + hidden_states = conv_layer(hidden_states) + + return hidden_states + + +class ContextPooler(nn.Module): + def __init__(self, config): + super().__init__() + self.dense = nn.Linear(config.pooler_hidden_size, config.pooler_hidden_size) + self.dropout = StableDropout(config.pooler_dropout) + self.config = config + + def forward(self, hidden_states): + # We "pool" the model by simply taking the hidden state corresponding + # to the first token. + + context_token = hidden_states[:, 0] + context_token = self.dropout(context_token) + pooled_output = self.dense(context_token) + pooled_output = ACT2FN[self.config.pooler_hidden_act](pooled_output) + return pooled_output + + @property + def output_dim(self): + return self.config.hidden_size + + +class XSoftmax(torch.autograd.Function): + """ + Masked Softmax which is optimized for saving memory + + Args: + input (`torch.tensor`): The input tensor that will apply softmax. + mask (`torch.IntTensor`): + The mask matrix where 0 indicate that element will be ignored in the softmax calculation. + dim (int): The dimension that will apply softmax + + Example: + + ```python + >>> import torch + >>> from transformers.models.deberta_v2.modeling_deberta_v2 import XSoftmax + + >>> # Make a tensor + >>> x = torch.randn([4, 20, 100]) + + >>> # Create a mask + >>> mask = (x > 0).int() + + >>> # Specify the dimension to apply softmax + >>> dim = -1 + + >>> y = XSoftmax.apply(x, mask, dim) + ```""" + + @staticmethod + def forward(ctx, input, mask, dim): + ctx.dim = dim + rmask = ~(mask.to(torch.bool)) + + output = input.masked_fill(rmask, torch.tensor(torch.finfo(input.dtype).min)) + output = torch.softmax(output, ctx.dim) + output.masked_fill_(rmask, 0) + ctx.save_for_backward(output) + return output + + @staticmethod + def backward(ctx, grad_output): + (output,) = ctx.saved_tensors + inputGrad = torch._softmax_backward_data(grad_output, output, ctx.dim, output.dtype) + return inputGrad, None, None + + @staticmethod + def symbolic(g, self, mask, dim): + import torch.onnx.symbolic_helper as sym_help + from torch.onnx.symbolic_opset9 import masked_fill, softmax + + mask_cast_value = g.op("Cast", mask, to_i=sym_help.cast_pytorch_to_onnx["Long"]) + r_mask = g.op( + "Cast", + g.op("Sub", g.op("Constant", value_t=torch.tensor(1, dtype=torch.int64)), mask_cast_value), + to_i=sym_help.cast_pytorch_to_onnx["Bool"], + ) + output = masked_fill( + g, self, r_mask, g.op("Constant", value_t=torch.tensor(torch.finfo(self.type().dtype()).min)) + ) + output = softmax(g, output, dim) + return masked_fill(g, output, r_mask, g.op("Constant", value_t=torch.tensor(0, dtype=torch.bool))) + + +class DropoutContext: + def __init__(self): + self.dropout = 0 + self.mask = None + self.scale = 1 + self.reuse_mask = True + + +class XDropout(torch.autograd.Function): + """Optimized dropout function to save computation and memory by using mask operation instead of multiplication.""" + + @staticmethod + def forward(ctx, input, local_ctx): + mask, dropout = get_mask(input, local_ctx) + ctx.scale = 1.0 / (1 - dropout) + if dropout > 0: + ctx.save_for_backward(mask) + return input.masked_fill(mask, 0) * ctx.scale + else: + return input + + @staticmethod + def backward(ctx, grad_output): + if ctx.scale > 1: + (mask,) = ctx.saved_tensors + return grad_output.masked_fill(mask, 0) * ctx.scale, None + else: + return grad_output, None + + @staticmethod + def symbolic(g: torch._C.Graph, input: torch._C.Value, local_ctx: float | DropoutContext) -> torch._C.Value: + from torch.onnx import symbolic_opset12 + + dropout_p = local_ctx + if isinstance(local_ctx, DropoutContext): + dropout_p = local_ctx.dropout + # StableDropout only calls this function when training. + train = True + # TODO: We should check if the opset_version being used to export + # is > 12 here, but there's no good way to do that. As-is, if the + # opset_version < 12, export will fail with a CheckerError. + # Once https://github.com/pytorch/pytorch/issues/78391 is fixed, do something like: + # if opset_version < 12: + # return torch.onnx.symbolic_opset9.dropout(g, input, dropout_p, train) + return symbolic_opset12.dropout(g, input, dropout_p, train) + + +class StableDropout(nn.Module): + """ + Optimized dropout module for stabilizing the training + + Args: + drop_prob (float): the dropout probabilities + """ + + def __init__(self, drop_prob): + super().__init__() + self.drop_prob = drop_prob + self.count = 0 + self.context_stack = None + + def forward(self, x): + """ + Call the module + + Args: + x (`torch.tensor`): The input tensor to apply dropout + """ + if self.training and self.drop_prob > 0: + return XDropout.apply(x, self.get_context()) + return x + + def clear_context(self): + self.count = 0 + self.context_stack = None + + def init_context(self, reuse_mask=True, scale=1): + if self.context_stack is None: + self.context_stack = [] + self.count = 0 + for c in self.context_stack: + c.reuse_mask = reuse_mask + c.scale = scale + + def get_context(self): + if self.context_stack is not None: + if self.count >= len(self.context_stack): + self.context_stack.append(DropoutContext()) + ctx = self.context_stack[self.count] + ctx.dropout = self.drop_prob + self.count += 1 + return ctx + else: + return self.drop_prob + + +class SEWDSelfOutput(nn.Module): + def __init__(self, config): + super().__init__() + self.dense = nn.Linear(config.hidden_size, config.hidden_size) + self.LayerNorm = LayerNorm(config.hidden_size, config.layer_norm_eps) + self.dropout = nn.Dropout(config.activation_dropout) + + def forward(self, hidden_states, input_tensor): + hidden_states = self.dense(hidden_states) + hidden_states = self.dropout(hidden_states) + hidden_states = self.LayerNorm(hidden_states + input_tensor) + return hidden_states + + +class DisentangledSelfAttention(nn.Module): + """ + Disentangled self-attention module + + Parameters: + config (`DebertaV2Config`): + A model config class instance with the configuration to build a new model. The schema is similar to + *BertConfig*, for more details, please refer [`DebertaV2Config`] + + """ + + def __init__(self, config): + super().__init__() + if config.hidden_size % config.num_attention_heads != 0: + raise ValueError( + f"The hidden size ({config.hidden_size}) is not a multiple of the number of attention " + f"heads ({config.num_attention_heads})" + ) + self.num_attention_heads = config.num_attention_heads + _attention_head_size = config.hidden_size // config.num_attention_heads + self.attention_head_size = getattr(config, "attention_head_size", _attention_head_size) + self.all_head_size = self.num_attention_heads * self.attention_head_size + self.query_proj = nn.Linear(config.hidden_size, self.all_head_size, bias=True) + self.key_proj = nn.Linear(config.hidden_size, self.all_head_size, bias=True) + self.value_proj = nn.Linear(config.hidden_size, self.all_head_size, bias=True) + + self.share_att_key = getattr(config, "share_att_key", False) + self.pos_att_type = config.pos_att_type if config.pos_att_type is not None else [] + self.relative_attention = getattr(config, "relative_attention", False) + + if self.relative_attention: + self.position_buckets = getattr(config, "position_buckets", -1) + self.max_relative_positions = getattr(config, "max_relative_positions", -1) + if self.max_relative_positions < 1: + self.max_relative_positions = config.max_position_embeddings + self.pos_ebd_size = self.max_relative_positions + if self.position_buckets > 0: + self.pos_ebd_size = self.position_buckets + + self.pos_dropout = StableDropout(config.activation_dropout) + + if not self.share_att_key: + if "c2p" in self.pos_att_type: + self.pos_key_proj = nn.Linear(config.hidden_size, self.all_head_size, bias=True) + if "p2c" in self.pos_att_type: + self.pos_query_proj = nn.Linear(config.hidden_size, self.all_head_size) + + self.dropout = StableDropout(config.attention_dropout) + + def transpose_for_scores(self, x, attention_heads): + new_x_shape = x.size()[:-1] + (attention_heads, -1) + x = x.view(new_x_shape) + return x.permute(0, 2, 1, 3).contiguous().view(-1, x.size(1), x.size(-1)) + + def forward( + self, + hidden_states, + attention_mask, + output_attentions=False, + query_states=None, + relative_pos=None, + rel_embeddings=None, + ): + """ + Call the module + + Args: + hidden_states (`torch.FloatTensor`): + Input states to the module usually the output from previous layer, it will be the Q,K and V in + *Attention(Q,K,V)* + + attention_mask (`torch.BoolTensor`): + An attention mask matrix of shape [*B*, *N*, *N*] where *B* is the batch size, *N* is the maximum + sequence length in which element [i,j] = *1* means the *i* th token in the input can attend to the *j* + th token. + + output_attentions (`bool`, *optional*): + Whether return the attention matrix. + + query_states (`torch.FloatTensor`, *optional*): + The *Q* state in *Attention(Q,K,V)*. + + relative_pos (`torch.LongTensor`): + The relative position encoding between the tokens in the sequence. It's of shape [*B*, *N*, *N*] with + values ranging in [*-max_relative_positions*, *max_relative_positions*]. + + rel_embeddings (`torch.FloatTensor`): + The embedding of relative distances. It's a tensor of shape [\\(2 \\times + \\text{max_relative_positions}\\), *hidden_size*]. + + + """ + if query_states is None: + query_states = hidden_states + query_layer = self.transpose_for_scores(self.query_proj(query_states), self.num_attention_heads) + key_layer = self.transpose_for_scores(self.key_proj(hidden_states), self.num_attention_heads) + value_layer = self.transpose_for_scores(self.value_proj(hidden_states), self.num_attention_heads) + + rel_att = None + # Take the dot product between "query" and "key" to get the raw attention scores. + scale_factor = 1 + if "c2p" in self.pos_att_type: + scale_factor += 1 + if "p2c" in self.pos_att_type: + scale_factor += 1 + scale = torch.sqrt(torch.tensor(query_layer.size(-1), dtype=torch.float) * scale_factor) + attention_scores = torch.bmm(query_layer, key_layer.transpose(-1, -2) / scale.to(dtype=query_layer.dtype)) + if self.relative_attention: + rel_embeddings = self.pos_dropout(rel_embeddings) + rel_att = self.disentangled_attention_bias( + query_layer, key_layer, relative_pos, rel_embeddings, scale_factor + ) + + if rel_att is not None: + attention_scores = attention_scores + rel_att + attention_scores = attention_scores.view( + -1, self.num_attention_heads, attention_scores.size(-2), attention_scores.size(-1) + ) + + # bsz x height x length x dimension + attention_probs = XSoftmax.apply(attention_scores, attention_mask, -1) + attention_probs = self.dropout(attention_probs) + context_layer = torch.bmm( + attention_probs.view(-1, attention_probs.size(-2), attention_probs.size(-1)), value_layer + ) + context_layer = ( + context_layer.view(-1, self.num_attention_heads, context_layer.size(-2), context_layer.size(-1)) + .permute(0, 2, 1, 3) + .contiguous() + ) + new_context_layer_shape = context_layer.size()[:-2] + (-1,) + context_layer = context_layer.view(new_context_layer_shape) + if output_attentions: + return (context_layer, attention_probs) + else: + return context_layer + + def disentangled_attention_bias(self, query_layer, key_layer, relative_pos, rel_embeddings, scale_factor): + if relative_pos is None: + q = query_layer.size(-2) + relative_pos = build_relative_position( + q, + key_layer.size(-2), + bucket_size=self.position_buckets, + max_position=self.max_relative_positions, + device=query_layer.device, + ) + if relative_pos.dim() == 2: + relative_pos = relative_pos.unsqueeze(0).unsqueeze(0) + elif relative_pos.dim() == 3: + relative_pos = relative_pos.unsqueeze(1) + # bsz x height x query x key + elif relative_pos.dim() != 4: + raise ValueError(f"Relative position ids must be of dim 2 or 3 or 4. {relative_pos.dim()}") + + att_span = self.pos_ebd_size + relative_pos = relative_pos.to(device=query_layer.device, dtype=torch.long) + + rel_embeddings = rel_embeddings[0 : att_span * 2, :].unsqueeze(0) + if self.share_att_key: + pos_query_layer = self.transpose_for_scores( + self.query_proj(rel_embeddings), self.num_attention_heads + ).repeat(query_layer.size(0) // self.num_attention_heads, 1, 1) + pos_key_layer = self.transpose_for_scores(self.key_proj(rel_embeddings), self.num_attention_heads).repeat( + query_layer.size(0) // self.num_attention_heads, 1, 1 + ) + else: + if "c2p" in self.pos_att_type: + pos_key_layer = self.transpose_for_scores( + self.pos_key_proj(rel_embeddings), self.num_attention_heads + ).repeat(query_layer.size(0) // self.num_attention_heads, 1, 1) # .split(self.all_head_size, dim=-1) + if "p2c" in self.pos_att_type: + pos_query_layer = self.transpose_for_scores( + self.pos_query_proj(rel_embeddings), self.num_attention_heads + ).repeat(query_layer.size(0) // self.num_attention_heads, 1, 1) # .split(self.all_head_size, dim=-1) + + score = 0 + # content->position + if "c2p" in self.pos_att_type: + scale = torch.sqrt(torch.tensor(pos_key_layer.size(-1), dtype=torch.float) * scale_factor) + c2p_att = torch.bmm(query_layer, pos_key_layer.transpose(-1, -2)) + c2p_pos = torch.clamp(relative_pos + att_span, 0, att_span * 2 - 1) + c2p_att = torch.gather( + c2p_att, + dim=-1, + index=c2p_pos.squeeze(0).expand([query_layer.size(0), query_layer.size(1), relative_pos.size(-1)]), + ) + score += c2p_att / scale.to(dtype=c2p_att.dtype) + + # position->content + if "p2c" in self.pos_att_type: + scale = torch.sqrt(torch.tensor(pos_query_layer.size(-1), dtype=torch.float) * scale_factor) + if key_layer.size(-2) != query_layer.size(-2): + r_pos = build_relative_position( + key_layer.size(-2), + key_layer.size(-2), + bucket_size=self.position_buckets, + max_position=self.max_relative_positions, + device=query_layer.device, + ) + r_pos = r_pos.unsqueeze(0) + else: + r_pos = relative_pos + + p2c_pos = torch.clamp(-r_pos + att_span, 0, att_span * 2 - 1) + p2c_att = torch.bmm(key_layer, pos_query_layer.transpose(-1, -2)) + p2c_att = torch.gather( + p2c_att, + dim=-1, + index=p2c_pos.squeeze(0).expand([query_layer.size(0), key_layer.size(-2), key_layer.size(-2)]), + ).transpose(-1, -2) + score += p2c_att / scale.to(dtype=p2c_att.dtype) + + return score + + +class SEWDAttention(nn.Module): + def __init__(self, config): + super().__init__() + self.self = DisentangledSelfAttention(config) + self.output = SEWDSelfOutput(config) + self.config = config + + def forward( + self, + hidden_states, + attention_mask, + output_attentions=False, + query_states=None, + relative_pos=None, + rel_embeddings=None, + ): + self_output = self.self( + hidden_states, + attention_mask, + output_attentions, + query_states=query_states, + relative_pos=relative_pos, + rel_embeddings=rel_embeddings, + ) + if output_attentions: + self_output, att_matrix = self_output + if query_states is None: + query_states = hidden_states + attention_output = self.output(self_output, query_states) + + if output_attentions: + return (attention_output, att_matrix) + else: + return attention_output + + +# Copied from transformers.models.bert.modeling_bert.BertIntermediate with Bert->SEWD +class SEWDIntermediate(nn.Module): + def __init__(self, config): + super().__init__() + self.dense = nn.Linear(config.hidden_size, config.intermediate_size) + if isinstance(config.hidden_act, str): + self.intermediate_act_fn = ACT2FN[config.hidden_act] + else: + self.intermediate_act_fn = config.hidden_act + + def forward(self, hidden_states: torch.Tensor) -> torch.Tensor: + hidden_states = self.dense(hidden_states) + hidden_states = self.intermediate_act_fn(hidden_states) + return hidden_states + + +class SEWDOutput(nn.Module): + def __init__(self, config): + super().__init__() + self.dense = nn.Linear(config.intermediate_size, config.hidden_size) + self.LayerNorm = LayerNorm(config.hidden_size, config.layer_norm_eps) + self.dropout = nn.Dropout(config.activation_dropout) + self.config = config + + def forward(self, hidden_states, input_tensor): + hidden_states = self.dense(hidden_states) + hidden_states = self.dropout(hidden_states) + hidden_states = self.LayerNorm(hidden_states + input_tensor) + return hidden_states + + +class SEWDLayer(GradientCheckpointingLayer): + def __init__(self, config): + super().__init__() + self.attention = SEWDAttention(config) + self.intermediate = SEWDIntermediate(config) + self.output = SEWDOutput(config) + + def forward( + self, + hidden_states, + attention_mask, + query_states=None, + relative_pos=None, + rel_embeddings=None, + output_attentions=False, + ): + attention_output = self.attention( + hidden_states, + attention_mask, + output_attentions=output_attentions, + query_states=query_states, + relative_pos=relative_pos, + rel_embeddings=rel_embeddings, + ) + if output_attentions: + attention_output, att_matrix = attention_output + intermediate_output = self.intermediate(attention_output) + layer_output = self.output(intermediate_output, attention_output) + if output_attentions: + return (layer_output, att_matrix) + else: + return layer_output + + +class ConvLayer(nn.Module): + def __init__(self, config): + super().__init__() + kernel_size = getattr(config, "conv_kernel_size", 3) + groups = getattr(config, "conv_groups", 1) + self.conv_act = getattr(config, "conv_act", "tanh") + self.conv = nn.Conv1d( + config.hidden_size, config.hidden_size, kernel_size, padding=(kernel_size - 1) // 2, groups=groups + ) + self.LayerNorm = LayerNorm(config.hidden_size, config.layer_norm_eps) + self.dropout = StableDropout(config.hidden_dropout_prob) + self.config = config + + def forward(self, hidden_states, residual_states, input_mask): + out = self.conv(hidden_states.permute(0, 2, 1).contiguous()).permute(0, 2, 1).contiguous() + rmask = (1 - input_mask).bool() + out.masked_fill_(rmask.unsqueeze(-1).expand(out.size()), 0) + out = ACT2FN[self.conv_act](self.dropout(out)) + + layer_norm_input = residual_states + out + output = self.LayerNorm(layer_norm_input).to(layer_norm_input) + + if input_mask is None: + output_states = output + else: + if input_mask.dim() != layer_norm_input.dim(): + if input_mask.dim() == 4: + input_mask = input_mask.squeeze(1).squeeze(1) + input_mask = input_mask.unsqueeze(2) + + input_mask = input_mask.to(output.dtype) + output_states = output * input_mask + + return output_states + + +class SEWDTransformerEncoder(nn.Module): + """Modified BertEncoder with relative position bias support""" + + def __init__(self, config): + super().__init__() + + self.layer = nn.ModuleList([SEWDLayer(config) for _ in range(config.num_hidden_layers)]) + self.relative_attention = getattr(config, "relative_attention", False) + + if self.relative_attention: + self.max_relative_positions = getattr(config, "max_relative_positions", -1) + if self.max_relative_positions < 1: + self.max_relative_positions = config.max_position_embeddings + + self.position_buckets = getattr(config, "position_buckets", -1) + pos_ebd_size = self.max_relative_positions * 2 + + if self.position_buckets > 0: + pos_ebd_size = self.position_buckets * 2 + + self.rel_embeddings = nn.Embedding(pos_ebd_size, config.hidden_size) + + self.norm_rel_ebd = [x.strip() for x in getattr(config, "norm_rel_ebd", "none").lower().split("|")] + + if "layer_norm" in self.norm_rel_ebd: + self.LayerNorm = LayerNorm(config.hidden_size, config.layer_norm_eps, elementwise_affine=True) + + self.conv = ConvLayer(config) if getattr(config, "conv_kernel_size", 0) > 0 else None + self.gradient_checkpointing = False + + def get_rel_embedding(self): + rel_embeddings = self.rel_embeddings.weight if self.relative_attention else None + if rel_embeddings is not None and ("layer_norm" in self.norm_rel_ebd): + rel_embeddings = self.LayerNorm(rel_embeddings) + return rel_embeddings + + def get_attention_mask(self, attention_mask): + if attention_mask.dim() <= 2: + extended_attention_mask = attention_mask.unsqueeze(1).unsqueeze(2) + attention_mask = extended_attention_mask * extended_attention_mask.squeeze(-2).unsqueeze(-1) + elif attention_mask.dim() == 3: + attention_mask = attention_mask.unsqueeze(1) + + return attention_mask + + def get_rel_pos(self, hidden_states, query_states=None, relative_pos=None): + if self.relative_attention and relative_pos is None: + q = query_states.size(-2) if query_states is not None else hidden_states.size(-2) + relative_pos = build_relative_position( + q, + hidden_states.size(-2), + bucket_size=self.position_buckets, + max_position=self.max_relative_positions, + device=hidden_states.device, + ) + return relative_pos + + def forward( + self, + hidden_states, + attention_mask, + output_hidden_states=True, + output_attentions=False, + query_states=None, + relative_pos=None, + return_dict=True, + ): + if attention_mask.dim() <= 2: + input_mask = attention_mask + else: + input_mask = attention_mask.sum(-2) > 0 + attention_mask = self.get_attention_mask(attention_mask) + relative_pos = self.get_rel_pos(hidden_states, query_states, relative_pos) + + all_hidden_states = () if output_hidden_states else None + all_attentions = () if output_attentions else None + + if isinstance(hidden_states, Sequence): + next_kv = hidden_states[0] + else: + next_kv = hidden_states + rel_embeddings = self.get_rel_embedding() + output_states = next_kv + for i, layer_module in enumerate(self.layer): + if output_hidden_states: + all_hidden_states = all_hidden_states + (output_states,) + + output_states = layer_module( + next_kv, + attention_mask, + query_states=query_states, + relative_pos=relative_pos, + rel_embeddings=rel_embeddings, + output_attentions=output_attentions, + ) + + if output_attentions: + output_states, att_m = output_states + + if i == 0 and self.conv is not None: + output_states = self.conv(hidden_states, output_states, input_mask) + + if query_states is not None: + query_states = output_states + if isinstance(hidden_states, Sequence): + next_kv = hidden_states[i + 1] if i + 1 < len(self.layer) else None + else: + next_kv = output_states + + if output_attentions: + all_attentions = all_attentions + (att_m,) + + if output_hidden_states: + all_hidden_states = all_hidden_states + (output_states,) + + if not return_dict: + return tuple(v for v in [output_states, all_hidden_states, all_attentions] if v is not None) + return BaseModelOutput( + last_hidden_state=output_states, hidden_states=all_hidden_states, attentions=all_attentions + ) + + +class SEWDEncoder(nn.Module): + def __init__(self, config): + super().__init__() + self.config = config + self.pos_conv_embed = SEWDPositionalConvEmbedding(config) + self.pool = nn.AvgPool1d(config.squeeze_factor, config.squeeze_factor) + self.encoder = SEWDTransformerEncoder(config) + self.upsample = SEWDUpsampling(config) + self.gradient_checkpointing = False + + def forward( + self, + hidden_states: torch.tensor, + attention_mask: torch.Tensor | None = None, + output_attentions: bool = False, + output_hidden_states: bool = False, + return_dict: bool = True, + ): + max_encoder_length = hidden_states.shape[1] // self.config.squeeze_factor + if attention_mask is None: + attention_mask = torch.ones( + (hidden_states.shape[0], max_encoder_length), dtype=torch.long, device=hidden_states.device + ) + else: + # make sure padded tokens output 0 + expand_attention_mask = attention_mask.unsqueeze(-1).repeat(1, 1, hidden_states.shape[2]) + hidden_states[~expand_attention_mask.bool()] = 0.0 + + input_lengths = (attention_mask.long()).sum(-1) + # apply pooling formula to get real output_lengths + output_lengths = input_lengths // self.config.squeeze_factor + attention_ids = ( + torch.arange(0, max_encoder_length, device=output_lengths.device) + .view(1, -1) + .expand(output_lengths.shape[0], -1) + ) + attention_mask = (attention_ids < output_lengths.view(-1, 1)).long() + + n_input_timesteps = hidden_states.shape[1] + + hidden_states = hidden_states.transpose(1, 2) + position_embeddings = self.pos_conv_embed(hidden_states) + pooled_hidden_states = self.pool(hidden_states) + min_length = min(position_embeddings.size(-1), pooled_hidden_states.size(-1)) + hidden_states = pooled_hidden_states[..., :min_length] + position_embeddings[..., :min_length] + hidden_states = hidden_states.transpose(1, 2) + + encoder_outputs = self.encoder(hidden_states, attention_mask, output_hidden_states, output_attentions) + + hidden_states = self.upsample(encoder_outputs.last_hidden_state) + if hidden_states.shape[1] < n_input_timesteps: + hidden_states = nn.functional.pad(hidden_states, (0, 0, 0, n_input_timesteps - hidden_states.shape[1])) + + if not return_dict: + return tuple( + v for v in [hidden_states, encoder_outputs.hidden_states, encoder_outputs.attentions] if v is not None + ) + return BaseModelOutput( + last_hidden_state=hidden_states, + hidden_states=encoder_outputs.hidden_states, + attentions=encoder_outputs.attentions, + ) + + +@auto_docstring +class SEWDPreTrainedModel(PreTrainedModel): + config: SEWDConfig + base_model_prefix = "sew-d" + main_input_name = "input_values" + input_modalities = "audio" + supports_gradient_checkpointing = True + + @torch.no_grad() + def _init_weights(self, module): + """Initialize the weights""" + if isinstance(module, SEWDPositionalConvEmbedding): + init.normal_( + module.conv.weight, + mean=0, + std=2 * math.sqrt(1 / (module.conv.kernel_size[0] * module.conv.in_channels)), + ) + init.constant_(module.conv.bias, 0) + elif isinstance(module, nn.Linear): + init.normal_(module.weight, mean=0.0, std=self.config.initializer_range) + elif isinstance(module, (nn.LayerNorm, nn.GroupNorm)): + init.zeros_(module.bias) + init.ones_(module.weight) + elif isinstance(module, nn.Conv1d): + if is_deepspeed_zero3_enabled(): + import deepspeed + + if hasattr(module, "weight_v") and hasattr(module, "weight_g"): + with deepspeed.zero.GatheredParameters([module.weight_v, module.weight_g], modifier_rank=0): + init.kaiming_normal_(module.weight) + else: + with deepspeed.zero.GatheredParameters(module.weight, modifier_rank=0): + init.kaiming_normal_(module.weight) + else: + init.kaiming_normal_(module.weight) + elif isinstance(module, nn.Embedding): + init.normal_(module.weight, mean=0.0, std=self.config.initializer_range) + # Here we need the check explicitly, as we slice the weight in the `zeros_` call, so it looses the flag + if module.padding_idx is not None and not getattr(module.weight, "_is_hf_initialized", False): + init.zeros_(module.weight[module.padding_idx]) + + if isinstance(module, (nn.Linear, nn.Conv1d)) and module.bias is not None: + init.zeros_(module.bias) + + def _get_feat_extract_output_lengths(self, input_lengths: torch.LongTensor | int): + """ + Computes the output length of the convolutional layers + """ + + def _conv_out_length(input_length, kernel_size, stride): + # 1D convolutional layer output length formula taken + # from https://pytorch.org/docs/stable/generated/torch.nn.Conv1d.html + return torch.div(input_length - kernel_size, stride, rounding_mode="floor") + 1 + + for kernel_size, stride in zip(self.config.conv_kernel, self.config.conv_stride): + input_lengths = _conv_out_length(input_lengths, kernel_size, stride) + + return input_lengths + + def _get_feature_vector_attention_mask(self, feature_vector_length: int, attention_mask: torch.LongTensor): + output_lengths = self._get_feat_extract_output_lengths(attention_mask.sum(-1)).to(torch.long) + batch_size = attention_mask.shape[0] + + attention_mask = torch.zeros( + (batch_size, feature_vector_length), dtype=attention_mask.dtype, device=attention_mask.device + ) + # these two operations makes sure that all values before the output lengths idxs are attended to + attention_mask[(torch.arange(attention_mask.shape[0], device=attention_mask.device), output_lengths - 1)] = 1 + attention_mask = attention_mask.flip([-1]).cumsum(-1).flip([-1]).bool() + return attention_mask + + +@auto_docstring +# Copied from transformers.models.sew.modeling_sew.SEWModel with SEW->SEWD, layer_norm_eps->feature_layer_norm_eps +class SEWDModel(SEWDPreTrainedModel): + def __init__(self, config: SEWDConfig): + super().__init__(config) + self.config = config + self.feature_extractor = SEWDFeatureEncoder(config) + self.layer_norm = nn.LayerNorm(config.conv_dim[-1], eps=config.feature_layer_norm_eps) + + self.project_features = config.conv_dim[-1] != config.hidden_size + if self.project_features: + self.feature_projection = nn.Linear(config.conv_dim[-1], config.hidden_size) + self.feature_dropout = nn.Dropout(config.feat_proj_dropout) + + if config.mask_time_prob > 0.0 or config.mask_feature_prob > 0.0: + self.masked_spec_embed = nn.Parameter(torch.Tensor(config.hidden_size).uniform_()) + + self.encoder = SEWDEncoder(config) + + # Initialize weights and apply final processing + self.post_init() + + # Copied from transformers.models.wav2vec2.modeling_wav2vec2.Wav2Vec2Model._mask_hidden_states + def _mask_hidden_states( + self, + hidden_states: torch.FloatTensor, + mask_time_indices: torch.FloatTensor | None = None, + attention_mask: torch.LongTensor | None = None, + ): + """ + Masks extracted features along time axis and/or along feature axis according to + [SpecAugment](https://huggingface.co/papers/1904.08779). + """ + + # `config.apply_spec_augment` can set masking to False + if not getattr(self.config, "apply_spec_augment", True): + return hidden_states + + # generate indices & apply SpecAugment along time axis + batch_size, sequence_length, hidden_size = hidden_states.size() + + if mask_time_indices is not None: + # apply SpecAugment along time axis with given mask_time_indices + hidden_states[mask_time_indices] = self.masked_spec_embed.to(hidden_states.dtype) + elif self.config.mask_time_prob > 0 and self.training: + mask_time_indices = _compute_mask_indices( + (batch_size, sequence_length), + mask_prob=self.config.mask_time_prob, + mask_length=self.config.mask_time_length, + attention_mask=attention_mask, + min_masks=self.config.mask_time_min_masks, + ) + mask_time_indices = torch.tensor(mask_time_indices, device=hidden_states.device, dtype=torch.bool) + hidden_states[mask_time_indices] = self.masked_spec_embed.to(hidden_states.dtype) + + if self.config.mask_feature_prob > 0 and self.training: + # generate indices & apply SpecAugment along feature axis + mask_feature_indices = _compute_mask_indices( + (batch_size, hidden_size), + mask_prob=self.config.mask_feature_prob, + mask_length=self.config.mask_feature_length, + min_masks=self.config.mask_feature_min_masks, + ) + mask_feature_indices = torch.tensor(mask_feature_indices, device=hidden_states.device, dtype=torch.bool) + mask_feature_indices = mask_feature_indices[:, None].expand(-1, sequence_length, -1) + hidden_states[mask_feature_indices] = 0 + + return hidden_states + + @auto_docstring + def forward( + self, + input_values: torch.Tensor | None, + attention_mask: torch.Tensor | None = None, + mask_time_indices: torch.FloatTensor | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + **kwargs, + ) -> tuple | BaseModelOutput: + r""" + mask_time_indices (`torch.BoolTensor` of shape `(batch_size, sequence_length)`, *optional*): + Indices to mask extracted features for contrastive loss. When in training mode, model learns to predict + masked extracted features in *config.proj_codevector_dim* space. + """ + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + extract_features = self.feature_extractor(input_values) + extract_features = extract_features.transpose(1, 2) + extract_features = self.layer_norm(extract_features) + + if self.project_features: + extract_features = self.feature_projection(extract_features) + hidden_states = self.feature_dropout(extract_features) + + if attention_mask is not None: + # compute reduced attention_mask corresponding to feature vectors + attention_mask = self._get_feature_vector_attention_mask(hidden_states.shape[1], attention_mask) + + hidden_states = self._mask_hidden_states(hidden_states, mask_time_indices=mask_time_indices) + + encoder_outputs = self.encoder( + hidden_states, + attention_mask=attention_mask, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + + hidden_states = encoder_outputs[0] + + if not return_dict: + return (hidden_states,) + encoder_outputs[1:] + + return BaseModelOutput( + last_hidden_state=hidden_states, + hidden_states=encoder_outputs.hidden_states, + attentions=encoder_outputs.attentions, + ) + + +@auto_docstring( + custom_intro=""" + SEW-D Model with a `language modeling` head on top for Connectionist Temporal Classification (CTC). + """ +) +# Copied from transformers.models.wav2vec2.modeling_wav2vec2.Wav2Vec2ForCTC with Wav2Vec2->SEWD, wav2vec2->sew_d, WAV2VEC2->SEWD +class SEWDForCTC(SEWDPreTrainedModel): + def __init__(self, config, target_lang: str | None = None): + r""" + target_lang (`str`, *optional*): + Language id of adapter weights. Adapter weights are stored in the format adapter..safetensors or + adapter..bin. Only relevant when using an instance of [`SEWDForCTC`] with adapters. Uses 'eng' by + default. + """ + super().__init__(config) + + self.sew_d = SEWDModel(config) + self.dropout = nn.Dropout(config.final_dropout) + + self.target_lang = target_lang + + if config.vocab_size is None: + raise ValueError( + f"You are trying to instantiate {self.__class__} with a configuration that " + "does not define the vocabulary size of the language model head. Please " + "instantiate the model as follows: `SEWDForCTC.from_pretrained(..., vocab_size=vocab_size)`. " + "or define `vocab_size` of your model's configuration." + ) + output_hidden_size = ( + config.output_hidden_size if hasattr(config, "add_adapter") and config.add_adapter else config.hidden_size + ) + self.lm_head = nn.Linear(output_hidden_size, config.vocab_size) + + # Initialize weights and apply final processing + self.post_init() + + def tie_weights(self, **kwargs): + """ + This method overwrites [`~PreTrainedModel.tie_weights`] so that adapter weights can be correctly loaded when + passing `target_lang=...` to `from_pretrained(...)`. + + This method is **not** supposed to be called by the user and is prone to be changed in the future. + """ + + if get_torch_context_manager_or_global_device() == torch.device("meta"): + return + + # Note that `tie_weights` is usually used to tie input and output embedding weights. The method is re-purposed to + # correctly load adapter layers for SEWD so that we do not have to introduce a new API to + # [`PreTrainedModel`]. While slightly hacky, SEWD never has to tie input and output embeddings, so that it is + # ok to repurpose this function here. + target_lang = self.target_lang + + if target_lang is not None and getattr(self.config, "adapter_attn_dim", None) is None: + raise ValueError(f"Cannot pass `target_lang`: {target_lang} if `config.adapter_attn_dim` is not defined.") + elif target_lang is None and getattr(self.config, "adapter_attn_dim", None) is not None: + logger.info("By default `target_lang` is set to 'eng'.") + elif target_lang is not None: + self.load_adapter(target_lang, force_load=True) + + def freeze_feature_encoder(self): + """ + Calling this function will disable the gradient computation for the feature encoder so that its parameter will + not be updated during training. + """ + self.sew_d.feature_extractor._freeze_parameters() + + def freeze_base_model(self): + """ + Calling this function will disable the gradient computation for the base model so that its parameters will not + be updated during training. Only the classification head will be updated. + """ + for param in self.sew_d.parameters(): + param.requires_grad = False + + @auto_docstring + def forward( + self, + input_values: torch.Tensor | None, + attention_mask: torch.Tensor | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + labels: torch.Tensor | None = None, + **kwargs, + ) -> tuple | CausalLMOutput: + r""" + labels (`torch.LongTensor` of shape `(batch_size, target_length)`, *optional*): + Labels for connectionist temporal classification. Note that `target_length` has to be smaller or equal to + the sequence length of the output logits. Indices are selected in `[-100, 0, ..., config.vocab_size - 1]`. + All labels set to `-100` are ignored (masked), the loss is only computed for labels in `[0, ..., + config.vocab_size - 1]`. + """ + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + if labels is not None and labels.max() >= self.config.vocab_size: + raise ValueError(f"Label values must be <= vocab_size: {self.config.vocab_size}") + + outputs = self.sew_d( + input_values, + attention_mask=attention_mask, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + + hidden_states = outputs[0] + hidden_states = self.dropout(hidden_states) + + logits = self.lm_head(hidden_states) + + loss = None + if labels is not None: + # retrieve loss input_lengths from attention_mask + attention_mask = ( + attention_mask if attention_mask is not None else torch.ones_like(input_values, dtype=torch.long) + ) + input_lengths = self._get_feat_extract_output_lengths(attention_mask.sum(-1)).to(torch.long) + + # assuming that padded tokens are filled with -100 + # when not being attended to + labels_mask = labels >= 0 + target_lengths = labels_mask.sum(-1) + flattened_targets = labels.masked_select(labels_mask) + + # ctc_loss doesn't support fp16 + log_probs = nn.functional.log_softmax(logits, dim=-1, dtype=torch.float32).transpose(0, 1) + + with torch.backends.cudnn.flags(enabled=False): + loss = nn.functional.ctc_loss( + log_probs, + flattened_targets, + input_lengths, + target_lengths, + blank=self.config.pad_token_id, + reduction=self.config.ctc_loss_reduction, + zero_infinity=self.config.ctc_zero_infinity, + ) + + if not return_dict: + output = (logits,) + outputs[_HIDDEN_STATES_START_POSITION:] + return ((loss,) + output) if loss is not None else output + + return CausalLMOutput( + loss=loss, logits=logits, hidden_states=outputs.hidden_states, attentions=outputs.attentions + ) + + +@auto_docstring( + custom_intro=""" + SEWD Model with a sequence classification head on top (a linear layer over the pooled output) for tasks like SUPERB + Keyword Spotting. + """ +) +# Copied from transformers.models.wav2vec2.modeling_wav2vec2.Wav2Vec2ForSequenceClassification with Wav2Vec2->SEWD, wav2vec2->sew_d, WAV2VEC2->SEWD +class SEWDForSequenceClassification(SEWDPreTrainedModel): + def __init__(self, config): + super().__init__(config) + + if hasattr(config, "add_adapter") and config.add_adapter: + raise ValueError( + "Sequence classification does not support the use of SEWD adapters (config.add_adapter=True)" + ) + self.sew_d = SEWDModel(config) + num_layers = config.num_hidden_layers + 1 # transformer layers + input embeddings + if config.use_weighted_layer_sum: + self.layer_weights = nn.Parameter(torch.ones(num_layers) / num_layers) + self.projector = nn.Linear(config.hidden_size, config.classifier_proj_size) + self.classifier = nn.Linear(config.classifier_proj_size, config.num_labels) + + # Initialize weights and apply final processing + self.post_init() + + def freeze_feature_encoder(self): + """ + Calling this function will disable the gradient computation for the feature encoder so that its parameter will + not be updated during training. + """ + self.sew_d.feature_extractor._freeze_parameters() + + def freeze_base_model(self): + """ + Calling this function will disable the gradient computation for the base model so that its parameters will not + be updated during training. Only the classification head will be updated. + """ + for param in self.sew_d.parameters(): + param.requires_grad = False + + @auto_docstring + def forward( + self, + input_values: torch.Tensor | None, + attention_mask: torch.Tensor | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + labels: torch.Tensor | None = None, + **kwargs, + ) -> tuple | SequenceClassifierOutput: + r""" + input_values (`torch.FloatTensor` of shape `(batch_size, sequence_length)`): + Float values of input raw speech waveform. Values can be obtained by loading a `.flac` or `.wav` audio file + into an array of type `list[float]`, a `numpy.ndarray` or a `torch.Tensor`, *e.g.* via the torchcodec library + (`pip install torchcodec`) or the soundfile library (`pip install soundfile`). + To prepare the array into `input_values`, the [`AutoProcessor`] should be used for padding and conversion + into a tensor of type `torch.FloatTensor`. See [`SEWDProcessor.__call__`] for details. + labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*): + Labels for computing the sequence classification/regression loss. Indices should be in `[0, ..., + config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If + `config.num_labels > 1` a classification loss is computed (Cross-Entropy). + """ + + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + output_hidden_states = True if self.config.use_weighted_layer_sum else output_hidden_states + + outputs = self.sew_d( + input_values, + attention_mask=attention_mask, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + ) + + if self.config.use_weighted_layer_sum: + hidden_states = outputs[_HIDDEN_STATES_START_POSITION] + hidden_states = torch.stack(hidden_states, dim=1) + norm_weights = nn.functional.softmax(self.layer_weights, dim=-1) + hidden_states = (hidden_states * norm_weights.view(-1, 1, 1)).sum(dim=1) + else: + hidden_states = outputs[0] + + hidden_states = self.projector(hidden_states) + if attention_mask is None: + pooled_output = hidden_states.mean(dim=1) + else: + padding_mask = self._get_feature_vector_attention_mask(hidden_states.shape[1], attention_mask) + expand_padding_mask = padding_mask.unsqueeze(-1).repeat(1, 1, hidden_states.shape[2]) + hidden_states[~expand_padding_mask] = 0.0 + pooled_output = hidden_states.sum(dim=1) / padding_mask.sum(dim=1).view(-1, 1) + + logits = self.classifier(pooled_output) + + loss = None + if labels is not None: + loss_fct = CrossEntropyLoss() + loss = loss_fct(logits.view(-1, self.config.num_labels), labels.view(-1)) + + if not return_dict: + output = (logits,) + outputs[_HIDDEN_STATES_START_POSITION:] + return ((loss,) + output) if loss is not None else output + + return SequenceClassifierOutput( + loss=loss, + logits=logits, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + ) + + +__all__ = ["SEWDForCTC", "SEWDForSequenceClassification", "SEWDModel", "SEWDPreTrainedModel"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/shieldgemma2/__init__.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/shieldgemma2/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..3eaa894027352f1dd928e853bec4eef131acd8e4 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/shieldgemma2/__init__.py @@ -0,0 +1,28 @@ +# Copyright 2025 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from typing import TYPE_CHECKING + +from ...utils import _LazyModule +from ...utils.import_utils import define_import_structure + + +if TYPE_CHECKING: + from .configuration_shieldgemma2 import * + from .modeling_shieldgemma2 import * + from .processing_shieldgemma2 import * +else: + import sys + + _file = globals()["__file__"] + sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__) diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/shieldgemma2/configuration_shieldgemma2.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/shieldgemma2/configuration_shieldgemma2.py new file mode 100644 index 0000000000000000000000000000000000000000..da619e723d1dcdcdde26980645b8c4eeeee0791d --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/shieldgemma2/configuration_shieldgemma2.py @@ -0,0 +1,117 @@ +# Copyright 2025 Google Inc. HuggingFace Inc. team. All rights reserved. +# +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +from ...configuration_utils import PreTrainedConfig +from ...utils import logging +from ..auto import CONFIG_MAPPING, AutoConfig + + +logger = logging.get_logger(__name__) + + +class ShieldGemma2Config(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`ShieldGemma2ForImageClassification`]. It is used to instantiate an + ShieldGemma2ForImageClassification according to the specified arguments, defining the model architecture. Instantiating a configuration + with the defaults will yield a similar configuration to that of the shieldgemma-2-4b-it. + + e.g. [google/gemma-3-4b](https://huggingface.co/google/gemma-3-4b) + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + text_config (`Union[ShieldGemma2TextConfig, dict]`, *optional*): + The config object of the text backbone. + vision_config (`Union[AutoConfig, dict]`, *optional*): + Custom vision config or dict. + mm_tokens_per_image (`int`, *optional*, defaults to 256): + The number of tokens per image embedding. + boi_token_index (`int`, *optional*, defaults to 255999): + The begin-of-image token index to wrap the image prompt. + eoi_token_index (`int`, *optional*, defaults to 256000): + The end-of-image token index to wrap the image prompt. + image_token_index (`int`, *optional*, defaults to 262144): + The image token index to encode the image prompt. + initializer_range (`float`, *optional*, defaults to 0.02): + The standard deviation of the truncated_normal_initializer for initializing all weight matrices. + + + Example: + + ```python + >>> from transformers import ShieldGemma2ForConditionalGeneration, ShieldGemma2Config, SiglipVisionConfig, ShieldGemma2TextConfig + + >>> # Initializing a Siglip-like vision config + >>> vision_config = SiglipVisionConfig() + + >>> # Initializing a ShieldGemma2 Text config + >>> text_config = ShieldGemma2TextConfig() + + >>> # Initializing a ShieldGemma2 gemma-3-4b style configuration + >>> configuration = ShieldGemma2Config(vision_config, text_config) + + >>> # Initializing a model from the gemma-3-4b style configuration + >>> model = ShieldGemma2TextConfig(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "shieldgemma2" + attribute_map = { + "image_token_id": "image_token_index", + "boi_token_id": "boi_token_index", + "eoi_token_id": "eoi_token_index", + } + sub_configs = {"text_config": AutoConfig, "vision_config": AutoConfig} + + def __init__( + self, + text_config=None, + vision_config=None, + mm_tokens_per_image: int = 256, + boi_token_index: int = 255_999, + eoi_token_index: int = 256_000, + image_token_index: int = 262_144, + initializer_range: float = 0.02, + **kwargs, + ): + if isinstance(vision_config, dict): + vision_config["model_type"] = vision_config.get("model_type", "siglip_vision_model") + vision_config = CONFIG_MAPPING[vision_config["model_type"]](**vision_config) + elif vision_config is None: + vision_config = CONFIG_MAPPING["siglip_vision_model"]() + + self.vision_config = vision_config + + if isinstance(text_config, dict): + text_config["model_type"] = text_config.get("model_type", "gemma3_text") + text_config = CONFIG_MAPPING[text_config["model_type"]](**text_config) + elif text_config is None: + text_config = CONFIG_MAPPING["gemma3_text"]() + + self.text_config = text_config + self.vision_config = vision_config + self.mm_tokens_per_image = mm_tokens_per_image + self.boi_token_index = boi_token_index + self.eoi_token_index = eoi_token_index + self.image_token_index = image_token_index + self.initializer_range = initializer_range + + super().__init__(**kwargs) + + +__all__ = ["ShieldGemma2Config"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/shieldgemma2/modeling_shieldgemma2.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/shieldgemma2/modeling_shieldgemma2.py new file mode 100644 index 0000000000000000000000000000000000000000..2e4944577f695d311328a3dadcdd322f56a8c5d5 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/shieldgemma2/modeling_shieldgemma2.py @@ -0,0 +1,139 @@ +# Copyright 2025 Google Inc. HuggingFace Inc. team. All rights reserved. +# +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from dataclasses import dataclass + +import torch + +from ...cache_utils import Cache +from ...modeling_outputs import ImageClassifierOutputWithNoAttention +from ...modeling_utils import PreTrainedModel +from ...utils import ( + auto_docstring, + logging, +) +from ..auto import AutoModelForImageTextToText +from .configuration_shieldgemma2 import ShieldGemma2Config + + +logger = logging.get_logger(__name__) + + +@dataclass +class ShieldGemma2ImageClassifierOutputWithNoAttention(ImageClassifierOutputWithNoAttention): + """ShieldGemma2 classifies imags as violative or not relative to a specific policy + Args: + """ + + probabilities: torch.Tensor | None = None + + +@auto_docstring +class ShieldGemma2ForImageClassification(PreTrainedModel): + config: ShieldGemma2Config + input_modalities = ("image", "text") + _checkpoint_conversion_mapping = { + "model.language_model.model": "model.model.language_model", + "model.vision_tower": "model.model.vision_tower", + "model.multi_modal_projector": "model.model.multi_modal_projector", + "model.language_model.lm_head": "model.lm_head", + } + + def __init__(self, config: ShieldGemma2Config): + super().__init__(config=config) + self.yes_token_index = getattr(config, "yes_token_index", 10_784) + self.no_token_index = getattr(config, "no_token_index", 3771) + self.model = AutoModelForImageTextToText.from_config(config=config) + self.post_init() + + def get_input_embeddings(self): + return self.model.get_decoder().get_input_embeddings() + + def set_input_embeddings(self, value): + self.model.get_decoder().set_input_embeddings(value) + + def get_output_embeddings(self): + return self.model.get_decoder().get_output_embeddings() + + def set_output_embeddings(self, new_embeddings): + self.model.get_decoder().set_output_embeddings(new_embeddings) + + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + pixel_values: torch.FloatTensor | None = None, + attention_mask: torch.Tensor | None = None, + position_ids: torch.LongTensor | None = None, + past_key_values: Cache | None = None, + token_type_ids: torch.LongTensor | None = None, + cache_position: torch.LongTensor | None = None, + inputs_embeds: torch.FloatTensor | None = None, + labels: torch.LongTensor | None = None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + logits_to_keep: int | torch.Tensor = 0, + **lm_kwargs, + ) -> ShieldGemma2ImageClassifierOutputWithNoAttention: + r""" + Returns: + A `ShieldGemma2ImageClassifierOutputWithNoAttention` instance containing the logits and probabilities + associated with the model predicting the `Yes` or `No` token as the response to that prompt, captured in the + following properties. + + * `logits` (`torch.Tensor` of shape `(batch_size, 2)`): + The first position along dim=1 is the logits for the `Yes` token and the second position along dim=1 is + the logits for the `No` token. + * `probabilities` (`torch.Tensor` of shape `(batch_size, 2)`): + The first position along dim=1 is the probability of predicting the `Yes` token and the second position + along dim=1 is the probability of predicting the `No` token. + + ShieldGemma prompts are constructed such that predicting the `Yes` token means the content *does violate* the + policy as described. If you are only interested in the violative condition, use + `violated = outputs.probabilities[:, 1]` to extract that slice from the output tensors. + + When used with the `ShieldGemma2Processor`, the `batch_size` will be equal to `len(images) * len(policies)`, + and the order within the batch will be img1_policy1, ... img1_policyN, ... imgM_policyN. + """ + outputs = self.model( + input_ids=input_ids, + pixel_values=pixel_values, + attention_mask=attention_mask, + position_ids=position_ids, + past_key_values=past_key_values, + token_type_ids=token_type_ids, + cache_position=cache_position, + inputs_embeds=inputs_embeds, + labels=labels, + use_cache=use_cache, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=return_dict, + logits_to_keep=logits_to_keep, + **lm_kwargs, + ) + logits = outputs.logits + selected_logits = logits[:, -1, [self.yes_token_index, self.no_token_index]] + probabilities = torch.softmax(selected_logits, dim=-1) + return ShieldGemma2ImageClassifierOutputWithNoAttention( + logits=selected_logits, + probabilities=probabilities, + ) + + +__all__ = [ + "ShieldGemma2ForImageClassification", +] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/shieldgemma2/processing_shieldgemma2.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/shieldgemma2/processing_shieldgemma2.py new file mode 100644 index 0000000000000000000000000000000000000000..04798f3774ee7e0090e5d7f90ae65d6138b81e66 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/shieldgemma2/processing_shieldgemma2.py @@ -0,0 +1,190 @@ +# Copyright 2025 Google Inc. HuggingFace Inc. team. All rights reserved. +# +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from collections.abc import Mapping, Sequence + +from ...feature_extraction_utils import BatchFeature +from ...image_utils import ImageInput +from ...processing_utils import Unpack +from ...utils import logging +from ..gemma3.processing_gemma3 import Gemma3Processor, Gemma3ProcessorKwargs + + +logger = logging.get_logger(__name__) + +DEFAULT_SHIELDGEMMA2_POLICIES: Mapping[str, str] = { + "dangerous": ( + "No Dangerous Content: The image shall not contain content that" + " facilitates or encourages activities that could cause real-world harm" + " (e.g., building firearms and explosive devices, promotion of" + " terrorism, instructions for suicide)." + ), + "sexual": ( + "No Sexually Explicit content: The image shall not contain content that" + " depicts explicit or graphic sexual acts (e.g., pornography, erotic" + " nudity, depictions of rape or sexual assault)." + ), + "violence": ( + "No Violence/Gore content: The image shall not contain content that" + " depicts shocking, sensational, or gratuitous violence (e.g.," + " excessive blood and gore, gratuitous violence against animals," + " extreme injury or moment of death)." + ), +} + + +class ShieldGemma2ProcessorKwargs(Gemma3ProcessorKwargs, total=False): + policies: Sequence[str] | None + custom_policies: Mapping[str, str] | None + _defaults = { + "text_kwargs": { + "padding": True, + }, + "images_kwargs": { + "do_pan_and_scan": False, + }, + } + + +class ShieldGemma2Processor(Gemma3Processor): + def __init__( + self, image_processor, tokenizer, chat_template=None, image_seq_length=256, policy_definitions=None, **kwargs + ): + """A processor for the ShieldGemma 2 model. + + Args: + image_processor: The image processor to use, typically a `Gemma3ImageProcessorFast` instance. + tokenizer: The tokenizer to use, typically a `GemmaTokenizerFast` instance. + chat_template: The chat template to use with this processor. Typically, this is unset as the processor + configuration on Hugging Face Hub includes this value already. + image_seq_length: The number of soft tokens per image. Typically, this is unset as the processor + configuration on Hugging Face Hub includes this value already. + policy_definitions: A mapping from policy name to its description in text used as the default policies to + classify images against. The policy descriptions are included in the text of the prompts generated by + this processor. Typically, this is unset as the processor configuration on Hugging Face Hub includes + the base policies ShieldGemma was trained on. + """ + super().__init__(image_processor, tokenizer, chat_template, image_seq_length, **kwargs) + if policy_definitions is None: + self.policy_definitions = DEFAULT_SHIELDGEMMA2_POLICIES + else: + self.policy_definitions = policy_definitions + + def __call__( + self, + images: ImageInput | None = None, + text=None, + **kwargs: Unpack[ShieldGemma2ProcessorKwargs], + ) -> BatchFeature: + """Generates a batch of inputs from the provided images. + + ShieldGemma was trained to classify image content for policy compliance using a specific prompt construction. + This processor generates a batch of such prompts from the provided images by: + + 1. Creating a list of conversations, one for each `` pair; + 2. Converting these conversations to text using `self.apply_chat_template()`; and + 3. Encoding the conversations and images using the same techniques as `Gemma3Processor`. + + Args: + images: A single image or a list of images to include in the batch. + text: Not supported. + videos: Not supported. + audio: Not supported. + kwargs: An optional dictionary of keyword arguments to configure the + processor. Possible values include: + + * `custom_policies`: Additional policy definitions that augment the `self.policy_definitions` passed + into the constructor. Note that `custom_policies` that share a key with `self.policy_definitions` + will override the policy description + * `policies`: (Optional) a list of keys in the joint `self.policy_definitions | custom_policies` + dictionary of specific interest for the provided images. If empty or None, prompts will be + generated for every key in the joint dictionary. + + Returns: + A `BatchFeature` containing `input_ids`, `pixel_values`, etc. where each Tensor is of shape + `(len(images) * len(policies), )`, and the order within the batch will be + img1_policy1, ... img1_policyN, ... imgM_policyN. + """ + if not images: + raise ValueError("ShieldGemma 2 needs images to classify") + elif not isinstance(images, Sequence): + images = [images] + + if not self.chat_template: + raise ValueError("ShieldGemma 2 requires the use of a specific chat template") + + common_kwargs = kwargs.setdefault("common_kwargs", {}) + if "return_tensors" in kwargs: + common_kwargs["return_tensors"] = kwargs.pop("return_tensors") + + # Disable pan and scan + images_kwargs = kwargs.setdefault("images_kwargs", {}) + if images_kwargs.get("do_pan_and_scan") is True: + logger.warning_once("ShieldGemma2 does not support pan and scan.") + images_kwargs["do_pan_and_scan"] = False + + # Enable padding on the batch during tokenization + text_kwargs = kwargs.setdefault("text_kwargs", {}) + if "padding" not in text_kwargs: + text_kwargs["padding"] = kwargs.pop("padding", True) + text_kwargs["padding_side"] = kwargs.pop("padding_side", "left") + + policy_definitions: Mapping[str, str] = { + **self.policy_definitions, + **kwargs.get("custom_policies", {}), + } + + if (policies := kwargs.get("policies")) is None: + policies = list(policy_definitions.keys()) + + # TODO(ryanmullins): Support images from PIL or URLs. + messages = [] + expanded_images = [] + for img in images: + if not isinstance(img, list): + img = [img] + elif len(img) > 1: + raise ValueError(f"SheildGemma can process at most one image per sample, but got {len(img)} images") + + for policy in policies: + if img: + messages.append( + [ + { + "role": "user", + "content": [ + {"type": "image"}, + {"type": "text", "text": policy_definitions[policy]}, + ], + } + ] + ) + else: + messages.append( + [ + { + "role": "user", + "content": [ + {"type": "text", "text": policy_definitions[policy]}, + ], + } + ] + ) + expanded_images.append(img) + + text = self.apply_chat_template(messages, tokenize=False) + return super().__call__(images=expanded_images, text=text, **kwargs) + + +__all__ = ["ShieldGemma2Processor"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/siglip/__init__.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/siglip/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..a5861f45f45b06bc01bbaa48f96fcc4f638fc590 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/siglip/__init__.py @@ -0,0 +1,31 @@ +# Copyright 2024 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from typing import TYPE_CHECKING + +from ...utils import _LazyModule +from ...utils.import_utils import define_import_structure + + +if TYPE_CHECKING: + from .configuration_siglip import * + from .image_processing_siglip import * + from .image_processing_siglip_fast import * + from .modeling_siglip import * + from .processing_siglip import * + from .tokenization_siglip import * +else: + import sys + + _file = globals()["__file__"] + sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__) diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/siglip/configuration_siglip.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/siglip/configuration_siglip.py new file mode 100644 index 0000000000000000000000000000000000000000..c73c3e0baf3fb70355aff6c9d4b316340516d6d8 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/siglip/configuration_siglip.py @@ -0,0 +1,262 @@ +# Copyright 2024 The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""Siglip model configuration""" + +from ...configuration_utils import PreTrainedConfig +from ...utils import logging + + +logger = logging.get_logger(__name__) + + +class SiglipTextConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`SiglipTextModel`]. It is used to instantiate a + Siglip text encoder according to the specified arguments, defining the model architecture. Instantiating a + configuration with the defaults will yield a similar configuration to that of the text encoder of the Siglip + [google/siglip-base-patch16-224](https://huggingface.co/google/siglip-base-patch16-224) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + vocab_size (`int`, *optional*, defaults to 32000): + Vocabulary size of the Siglip text model. Defines the number of different tokens that can be represented by + the `inputs_ids` passed when calling [`SiglipModel`]. + hidden_size (`int`, *optional*, defaults to 768): + Dimensionality of the encoder layers and the pooler layer. + intermediate_size (`int`, *optional*, defaults to 3072): + Dimensionality of the "intermediate" (i.e., feed-forward) layer in the Transformer encoder. + num_hidden_layers (`int`, *optional*, defaults to 12): + Number of hidden layers in the Transformer encoder. + num_attention_heads (`int`, *optional*, defaults to 12): + Number of attention heads for each attention layer in the Transformer encoder. + max_position_embeddings (`int`, *optional*, defaults to 64): + The maximum sequence length that this model might ever be used with. Typically set this to something large + just in case (e.g., 512 or 1024 or 2048). + hidden_act (`str` or `function`, *optional*, defaults to `"gelu_pytorch_tanh"`): + The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`, + `"relu"`, `"selu"` and `"gelu_new"` `"quick_gelu"` are supported. + layer_norm_eps (`float`, *optional*, defaults to 1e-06): + The epsilon used by the layer normalization layers. + attention_dropout (`float`, *optional*, defaults to 0.0): + The dropout ratio for the attention probabilities. + pad_token_id (`int`, *optional*, defaults to 1): + The id of the padding token in the vocabulary. + bos_token_id (`int`, *optional*, defaults to 49406): + The id of the beginning-of-sequence token in the vocabulary. + eos_token_id (`int`, *optional*, defaults to 49407): + The id of the end-of-sequence token in the vocabulary. + projection_size (`int`, *optional*, defaults to `hidden_size`): + The size of the projection head. + + Example: + + ```python + >>> from transformers import SiglipTextConfig, SiglipTextModel + + >>> # Initializing a SiglipTextConfig with google/siglip-base-patch16-224 style configuration + >>> configuration = SiglipTextConfig() + + >>> # Initializing a SiglipTextModel (with random weights) from the google/siglip-base-patch16-224 style configuration + >>> model = SiglipTextModel(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "siglip_text_model" + base_config_key = "text_config" + + def __init__( + self, + vocab_size=32000, + hidden_size=768, + intermediate_size=3072, + num_hidden_layers=12, + num_attention_heads=12, + max_position_embeddings=64, + hidden_act="gelu_pytorch_tanh", + layer_norm_eps=1e-6, + attention_dropout=0.0, + # This differs from `CLIPTokenizer`'s default and from openai/siglip + # See https://github.com/huggingface/transformers/pull/24773#issuecomment-1632287538 + pad_token_id=1, + bos_token_id=49406, + eos_token_id=49407, + projection_size=None, + **kwargs, + ): + super().__init__(**kwargs) + self.pad_token_id = pad_token_id + self.bos_token_id = bos_token_id + self.eos_token_id = eos_token_id + + self.vocab_size = vocab_size + self.hidden_size = hidden_size + self.intermediate_size = intermediate_size + self.num_hidden_layers = num_hidden_layers + self.num_attention_heads = num_attention_heads + self.max_position_embeddings = max_position_embeddings + self.layer_norm_eps = layer_norm_eps + self.hidden_act = hidden_act + self.attention_dropout = attention_dropout + self.projection_size = projection_size if projection_size is not None else hidden_size + + +class SiglipVisionConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`SiglipVisionModel`]. It is used to instantiate a + Siglip vision encoder according to the specified arguments, defining the model architecture. Instantiating a + configuration with the defaults will yield a similar configuration to that of the vision encoder of the Siglip + [google/siglip-base-patch16-224](https://huggingface.co/google/siglip-base-patch16-224) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + hidden_size (`int`, *optional*, defaults to 768): + Dimensionality of the encoder layers and the pooler layer. + intermediate_size (`int`, *optional*, defaults to 3072): + Dimensionality of the "intermediate" (i.e., feed-forward) layer in the Transformer encoder. + num_hidden_layers (`int`, *optional*, defaults to 12): + Number of hidden layers in the Transformer encoder. + num_attention_heads (`int`, *optional*, defaults to 12): + Number of attention heads for each attention layer in the Transformer encoder. + num_channels (`int`, *optional*, defaults to 3): + Number of channels in the input images. + image_size (`int`, *optional*, defaults to 224): + The size (resolution) of each image. + patch_size (`int`, *optional*, defaults to 16): + The size (resolution) of each patch. + hidden_act (`str` or `function`, *optional*, defaults to `"gelu_pytorch_tanh"`): + The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`, + `"relu"`, `"selu"` and `"gelu_new"` `"quick_gelu"` are supported. + layer_norm_eps (`float`, *optional*, defaults to 1e-06): + The epsilon used by the layer normalization layers. + attention_dropout (`float`, *optional*, defaults to 0.0): + The dropout ratio for the attention probabilities. + + Example: + + ```python + >>> from transformers import SiglipVisionConfig, SiglipVisionModel + + >>> # Initializing a SiglipVisionConfig with google/siglip-base-patch16-224 style configuration + >>> configuration = SiglipVisionConfig() + + >>> # Initializing a SiglipVisionModel (with random weights) from the google/siglip-base-patch16-224 style configuration + >>> model = SiglipVisionModel(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "siglip_vision_model" + base_config_key = "vision_config" + + def __init__( + self, + hidden_size=768, + intermediate_size=3072, + num_hidden_layers=12, + num_attention_heads=12, + num_channels=3, + image_size=224, + patch_size=16, + hidden_act="gelu_pytorch_tanh", + layer_norm_eps=1e-6, + attention_dropout=0.0, + **kwargs, + ): + super().__init__(**kwargs) + + self.hidden_size = hidden_size + self.intermediate_size = intermediate_size + self.num_hidden_layers = num_hidden_layers + self.num_attention_heads = num_attention_heads + self.num_channels = num_channels + self.patch_size = patch_size + self.image_size = image_size + self.attention_dropout = attention_dropout + self.layer_norm_eps = layer_norm_eps + self.hidden_act = hidden_act + + +class SiglipConfig(PreTrainedConfig): + r""" + [`SiglipConfig`] is the configuration class to store the configuration of a [`SiglipModel`]. It is used to + instantiate a Siglip model according to the specified arguments, defining the text model and vision model configs. + Instantiating a configuration with the defaults will yield a similar configuration to that of the Siglip + [google/siglip-base-patch16-224](https://huggingface.co/google/siglip-base-patch16-224) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + text_config (`dict`, *optional*): + Dictionary of configuration options used to initialize [`SiglipTextConfig`]. + vision_config (`dict`, *optional*): + Dictionary of configuration options used to initialize [`SiglipVisionConfig`]. + kwargs (*optional*): + Dictionary of keyword arguments. + + Example: + + ```python + >>> from transformers import SiglipConfig, SiglipModel + + >>> # Initializing a SiglipConfig with google/siglip-base-patch16-224 style configuration + >>> configuration = SiglipConfig() + + >>> # Initializing a SiglipModel (with random weights) from the google/siglip-base-patch16-224 style configuration + >>> model = SiglipModel(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + + >>> # We can also initialize a SiglipConfig from a SiglipTextConfig and a SiglipVisionConfig + >>> from transformers import SiglipTextConfig, SiglipVisionConfig + + >>> # Initializing a SiglipText and SiglipVision configuration + >>> config_text = SiglipTextConfig() + >>> config_vision = SiglipVisionConfig() + + >>> config = SiglipConfig(text_config=config_text, vision_config=config_vision) + ```""" + + model_type = "siglip" + sub_configs = {"text_config": SiglipTextConfig, "vision_config": SiglipVisionConfig} + + def __init__(self, text_config=None, vision_config=None, **kwargs): + if text_config is None: + text_config = SiglipTextConfig() + logger.info("`text_config` is `None`. Initializing the `SiglipTextConfig` with default values.") + elif isinstance(text_config, dict): + text_config = SiglipTextConfig(**text_config) + + if vision_config is None: + vision_config = SiglipVisionConfig() + logger.info("`vision_config` is `None`. initializing the `SiglipVisionConfig` with default values.") + elif isinstance(vision_config, dict): + vision_config = SiglipVisionConfig(**vision_config) + + self.text_config = text_config + self.vision_config = vision_config + self.initializer_factor = 1.0 + + super().__init__(**kwargs) + + +__all__ = ["SiglipConfig", "SiglipTextConfig", "SiglipVisionConfig"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/siglip/image_processing_siglip.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/siglip/image_processing_siglip.py new file mode 100644 index 0000000000000000000000000000000000000000..583b5f7202e275f8f48949aac9a102ad0787c568 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/siglip/image_processing_siglip.py @@ -0,0 +1,237 @@ +# Copyright 2024 The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""Image processor class for SigLIP.""" + +from ...image_processing_utils import BaseImageProcessor, BatchFeature, get_size_dict +from ...image_transforms import ( + convert_to_rgb, + resize, + to_channel_dimension_format, +) +from ...image_utils import ( + IMAGENET_STANDARD_MEAN, + IMAGENET_STANDARD_STD, + ChannelDimension, + ImageInput, + PILImageResampling, + infer_channel_dimension_format, + is_scaled_image, + make_flat_list_of_images, + to_numpy_array, + valid_images, + validate_preprocess_arguments, +) +from ...utils import TensorType, filter_out_non_signature_kwargs, is_vision_available, logging + + +logger = logging.get_logger(__name__) + + +if is_vision_available(): + import PIL + + +class SiglipImageProcessor(BaseImageProcessor): + r""" + Constructs a SigLIP image processor. + + Args: + do_resize (`bool`, *optional*, defaults to `True`): + Whether to resize the image's (height, width) dimensions to the specified `size`. Can be overridden by + `do_resize` in the `preprocess` method. + size (`dict[str, int]` *optional*, defaults to `{"height": 224, "width": 224}`): + Size of the image after resizing. Can be overridden by `size` in the `preprocess` method. + resample (`PILImageResampling`, *optional*, defaults to `Resampling.BICUBIC`): + Resampling filter to use if resizing the image. Can be overridden by `resample` in the `preprocess` method. + do_rescale (`bool`, *optional*, defaults to `True`): + Whether to rescale the image by the specified scale `rescale_factor`. Can be overridden by `do_rescale` in + the `preprocess` method. + rescale_factor (`int` or `float`, *optional*, defaults to `1/255`): + Scale factor to use if rescaling the image. Can be overridden by `rescale_factor` in the `preprocess` + method. + do_normalize (`bool`, *optional*, defaults to `True`): + Whether to normalize the image by the specified mean and standard deviation. Can be overridden by + `do_normalize` in the `preprocess` method. + image_mean (`float` or `list[float]`, *optional*, defaults to `[0.5, 0.5, 0.5]`): + Mean to use if normalizing the image. This is a float or list of floats the length of the number of + channels in the image. Can be overridden by the `image_mean` parameter in the `preprocess` method. + image_std (`float` or `list[float]`, *optional*, defaults to `[0.5, 0.5, 0.5]`): + Standard deviation to use if normalizing the image. This is a float or list of floats the length of the + number of channels in the image. Can be overridden by the `image_std` parameter in the `preprocess` method. + Can be overridden by the `image_std` parameter in the `preprocess` method. + do_convert_rgb (`bool`, *optional*, defaults to `True`): + Whether to convert the image to RGB. + """ + + model_input_names = ["pixel_values"] + + def __init__( + self, + do_resize: bool = True, + size: dict[str, int] | None = None, + resample: PILImageResampling = PILImageResampling.BICUBIC, + do_rescale: bool = True, + rescale_factor: int | float = 1 / 255, + do_normalize: bool = True, + image_mean: float | list[float] | None = None, + image_std: float | list[float] | None = None, + do_convert_rgb: bool | None = None, + **kwargs, + ) -> None: + super().__init__(**kwargs) + size = size if size is not None else {"height": 224, "width": 224} + image_mean = image_mean if image_mean is not None else IMAGENET_STANDARD_MEAN + image_std = image_std if image_std is not None else IMAGENET_STANDARD_STD + + self.do_resize = do_resize + self.size = size + self.resample = resample + self.do_rescale = do_rescale + self.rescale_factor = rescale_factor + self.do_normalize = do_normalize + self.image_mean = image_mean + self.image_std = image_std + self.do_convert_rgb = do_convert_rgb + + @filter_out_non_signature_kwargs() + def preprocess( + self, + images: ImageInput, + do_resize: bool | None = None, + size: dict[str, int] | None = None, + resample: PILImageResampling | None = None, + do_rescale: bool | None = None, + rescale_factor: float | None = None, + do_normalize: bool | None = None, + image_mean: float | list[float] | None = None, + image_std: float | list[float] | None = None, + return_tensors: str | TensorType | None = None, + data_format: ChannelDimension | None = ChannelDimension.FIRST, + input_data_format: str | ChannelDimension | None = None, + do_convert_rgb: bool | None = None, + ) -> PIL.Image.Image: + """ + Preprocess an image or batch of images. + + Args: + images (`ImageInput`): + Image to preprocess. Expects a single or batch of images with pixel values ranging from 0 to 255. If + passing in images with pixel values between 0 and 1, set `do_rescale=False`. + do_resize (`bool`, *optional*, defaults to `self.do_resize`): + Whether to resize the image. + size (`dict[str, int]`, *optional*, defaults to `self.size`): + Size of the image after resizing. + resample (`int`, *optional*, defaults to `self.resample`): + Resampling filter to use if resizing the image. This can be one of the enum `PILImageResampling`. Only + has an effect if `do_resize` is set to `True`. + do_rescale (`bool`, *optional*, defaults to `self.do_rescale`): + Whether to rescale the image. + rescale_factor (`float`, *optional*, defaults to `self.rescale_factor`): + Rescale factor to rescale the image by if `do_rescale` is set to `True`. + do_normalize (`bool`, *optional*, defaults to `self.do_normalize`): + Whether to normalize the image. + image_mean (`float` or `list[float]`, *optional*, defaults to `self.image_mean`): + Image mean to use for normalization. Only has an effect if `do_normalize` is set to `True`. + image_std (`float` or `list[float]`, *optional*, defaults to `self.image_std`): + Image standard deviation to use for normalization. Only has an effect if `do_normalize` is set to + `True`. + return_tensors (`str` or `TensorType`, *optional*): + The type of tensors to return. Can be one of: + - Unset: Return a list of `np.ndarray`. + - `TensorType.PYTORCH` or `'pt'`: Return a batch of type `torch.Tensor`. + - `TensorType.NUMPY` or `'np'`: Return a batch of type `np.ndarray`. + data_format (`ChannelDimension` or `str`, *optional*, defaults to `ChannelDimension.FIRST`): + The channel dimension format for the output image. Can be one of: + - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format. + - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format. + - Unset: Use the channel dimension format of the input image. + input_data_format (`ChannelDimension` or `str`, *optional*): + The channel dimension format for the input image. If unset, the channel dimension format is inferred + from the input image. Can be one of: + - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format. + - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format. + - `"none"` or `ChannelDimension.NONE`: image in (height, width) format. + do_convert_rgb (`bool`, *optional*, defaults to `self.do_convert_rgb`): + Whether to convert the image to RGB. + """ + do_resize = do_resize if do_resize is not None else self.do_resize + size = size if size is not None else self.size + size = get_size_dict(size, param_name="size", default_to_square=False) + resample = resample if resample is not None else self.resample + do_rescale = do_rescale if do_rescale is not None else self.do_rescale + rescale_factor = rescale_factor if rescale_factor is not None else self.rescale_factor + do_normalize = do_normalize if do_normalize is not None else self.do_normalize + image_mean = image_mean if image_mean is not None else self.image_mean + image_std = image_std if image_std is not None else self.image_std + do_convert_rgb = do_convert_rgb if do_convert_rgb is not None else self.do_convert_rgb + + images = self.fetch_images(images) + images = make_flat_list_of_images(images) + + if not valid_images(images): + raise ValueError("Invalid image type. Must be of type PIL.Image.Image, numpy.ndarray, or torch.Tensor") + validate_preprocess_arguments( + do_rescale=do_rescale, + rescale_factor=rescale_factor, + do_normalize=do_normalize, + image_mean=image_mean, + image_std=image_std, + do_resize=do_resize, + size=size, + resample=resample, + ) + if do_convert_rgb: + images = [convert_to_rgb(image) for image in images] + + # All transformations expect numpy arrays. + images = [to_numpy_array(image) for image in images] + + if do_rescale and is_scaled_image(images[0]): + logger.warning_once( + "It looks like you are trying to rescale already rescaled images. If the input" + " images have pixel values between 0 and 1, set `do_rescale=False` to avoid rescaling them again." + ) + + if input_data_format is None: + # We assume that all images have the same channel dimension format. + input_data_format = infer_channel_dimension_format(images[0]) + + if do_resize: + height, width = size["height"], size["width"] + images = [ + resize(image=image, size=(height, width), resample=resample, input_data_format=input_data_format) + for image in images + ] + + if do_rescale: + images = [ + self.rescale(image=image, scale=rescale_factor, input_data_format=input_data_format) + for image in images + ] + + if do_normalize: + images = [ + self.normalize(image=image, mean=image_mean, std=image_std, input_data_format=input_data_format) + for image in images + ] + + images = [ + to_channel_dimension_format(image, data_format, input_channel_dim=input_data_format) for image in images + ] + + data = {"pixel_values": images} + return BatchFeature(data=data, tensor_type=return_tensors) + + +__all__ = ["SiglipImageProcessor"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/siglip/image_processing_siglip_fast.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/siglip/image_processing_siglip_fast.py new file mode 100644 index 0000000000000000000000000000000000000000..e97cb29382aaa38173e667eea08ce2e756fb67f6 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/siglip/image_processing_siglip_fast.py @@ -0,0 +1,37 @@ +# Copyright 2024 The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""Fast Image processor class for SigLIP.""" + +from ...image_processing_utils_fast import BaseImageProcessorFast +from ...image_utils import ( + IMAGENET_STANDARD_MEAN, + IMAGENET_STANDARD_STD, + PILImageResampling, +) +from ...utils import auto_docstring + + +@auto_docstring +class SiglipImageProcessorFast(BaseImageProcessorFast): + resample = PILImageResampling.BICUBIC + image_mean = IMAGENET_STANDARD_MEAN + image_std = IMAGENET_STANDARD_STD + size = {"height": 224, "width": 224} + default_to_square = False + do_resize = True + do_rescale = True + do_normalize = True + + +__all__ = ["SiglipImageProcessorFast"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/siglip/modeling_siglip.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/siglip/modeling_siglip.py new file mode 100644 index 0000000000000000000000000000000000000000..a2b8778447bae6fb5f166573f2046e5c8b94e1f9 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/siglip/modeling_siglip.py @@ -0,0 +1,1020 @@ +# Copyright 2024 Google AI and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""PyTorch Siglip model.""" + +from collections.abc import Callable +from dataclasses import dataclass +from typing import Any + +import numpy as np +import torch +from torch import nn + +from ... import initialization as init +from ...activations import ACT2FN +from ...masking_utils import create_bidirectional_mask +from ...modeling_layers import GradientCheckpointingLayer +from ...modeling_outputs import BaseModelOutput, BaseModelOutputWithPooling, ImageClassifierOutput +from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel +from ...processing_utils import Unpack +from ...utils import ( + ModelOutput, + TransformersKwargs, + auto_docstring, + can_return_tuple, + torch_int, +) +from ...utils.generic import merge_with_config_defaults +from ...utils.output_capturing import capture_outputs +from .configuration_siglip import SiglipConfig, SiglipTextConfig, SiglipVisionConfig + + +@dataclass +@auto_docstring( + custom_intro=""" + Base class for vision model's outputs that also contains image embeddings of the pooling of the last hidden states. + """ +) +# Copied from transformers.models.clip.modeling_clip.CLIPVisionModelOutput with CLIP->Siglip +class SiglipVisionModelOutput(ModelOutput): + r""" + image_embeds (`torch.FloatTensor` of shape `(batch_size, output_dim)` *optional* returned when model is initialized with `with_projection=True`): + The image embeddings obtained by applying the projection layer to the pooler_output. + """ + + image_embeds: torch.FloatTensor | None = None + last_hidden_state: torch.FloatTensor | None = None + hidden_states: tuple[torch.FloatTensor, ...] | None = None + attentions: tuple[torch.FloatTensor, ...] | None = None + + +@dataclass +@auto_docstring( + custom_intro=""" + Base class for text model's outputs that also contains a pooling of the last hidden states. + """ +) +# Copied from transformers.models.clip.modeling_clip.CLIPTextModelOutput with CLIP->Siglip +class SiglipTextModelOutput(ModelOutput): + r""" + text_embeds (`torch.FloatTensor` of shape `(batch_size, output_dim)` *optional* returned when model is initialized with `with_projection=True`): + The text embeddings obtained by applying the projection layer to the pooler_output. + """ + + text_embeds: torch.FloatTensor | None = None + last_hidden_state: torch.FloatTensor | None = None + hidden_states: tuple[torch.FloatTensor, ...] | None = None + attentions: tuple[torch.FloatTensor, ...] | None = None + + +@dataclass +@auto_docstring +# Copied from transformers.models.clip.modeling_clip.CLIPOutput with CLIP->Siglip +class SiglipOutput(ModelOutput): + r""" + loss (`torch.FloatTensor` of shape `(1,)`, *optional*, returned when `return_loss` is `True`): + Contrastive loss for image-text similarity. + logits_per_image (`torch.FloatTensor` of shape `(image_batch_size, text_batch_size)`): + The scaled dot product scores between `image_embeds` and `text_embeds`. This represents the image-text + similarity scores. + logits_per_text (`torch.FloatTensor` of shape `(text_batch_size, image_batch_size)`): + The scaled dot product scores between `text_embeds` and `image_embeds`. This represents the text-image + similarity scores. + text_embeds (`torch.FloatTensor` of shape `(batch_size, output_dim`): + The text embeddings obtained by applying the projection layer to the pooled output of [`SiglipTextModel`]. + image_embeds (`torch.FloatTensor` of shape `(batch_size, output_dim`): + The image embeddings obtained by applying the projection layer to the pooled output of [`SiglipVisionModel`]. + text_model_output (`BaseModelOutputWithPooling`): + The output of the [`SiglipTextModel`]. + vision_model_output (`BaseModelOutputWithPooling`): + The output of the [`SiglipVisionModel`]. + """ + + loss: torch.FloatTensor | None = None + logits_per_image: torch.FloatTensor | None = None + logits_per_text: torch.FloatTensor | None = None + text_embeds: torch.FloatTensor | None = None + image_embeds: torch.FloatTensor | None = None + text_model_output: BaseModelOutputWithPooling = None + vision_model_output: BaseModelOutputWithPooling = None + + def to_tuple(self) -> tuple[Any]: + return tuple( + self[k] if k not in ["text_model_output", "vision_model_output"] else getattr(self, k).to_tuple() + for k in self.keys() + ) + + +class SiglipVisionEmbeddings(nn.Module): + def __init__(self, config: SiglipVisionConfig): + super().__init__() + self.config = config + self.embed_dim = config.hidden_size + self.image_size = config.image_size + self.patch_size = config.patch_size + + self.patch_embedding = nn.Conv2d( + in_channels=config.num_channels, + out_channels=self.embed_dim, + kernel_size=self.patch_size, + stride=self.patch_size, + padding="valid", + ) + + self.num_patches = (self.image_size // self.patch_size) ** 2 + self.num_positions = self.num_patches + self.position_embedding = nn.Embedding(self.num_positions, self.embed_dim) + self.register_buffer("position_ids", torch.arange(self.num_positions).expand((1, -1)), persistent=False) + + def interpolate_pos_encoding(self, embeddings: torch.Tensor, height: int, width: int) -> torch.Tensor: + """ + This method allows to interpolate the pre-trained position encodings, to be able to use the model on higher resolution + images. This method is also adapted to support torch.jit tracing and no class embeddings. + + Adapted from: + - https://github.com/facebookresearch/dino/blob/de9ee3df6cf39fac952ab558447af1fa1365362a/vision_transformer.py#L174-L194, and + - https://github.com/facebookresearch/dinov2/blob/e1277af2ba9496fbadf7aec6eba56e8d882d1e35/dinov2/models/vision_transformer.py#L179-L211 + """ + + num_patches = embeddings.shape[1] + num_positions = self.position_embedding.weight.shape[0] + + # always interpolate when tracing to ensure the exported model works for dynamic input shapes + if not torch.jit.is_tracing() and num_patches == num_positions and height == width: + return self.position_embedding(self.position_ids) + + patch_pos_embed = self.position_embedding.weight.unsqueeze(0) + + dim = embeddings.shape[-1] + + new_height = height // self.patch_size + new_width = width // self.patch_size + + sqrt_num_positions = torch_int(num_positions**0.5) + patch_pos_embed = patch_pos_embed.reshape(1, sqrt_num_positions, sqrt_num_positions, dim) + patch_pos_embed = patch_pos_embed.permute(0, 3, 1, 2) + + patch_pos_embed = nn.functional.interpolate( + patch_pos_embed, + size=(new_height, new_width), + mode="bicubic", + align_corners=False, + ) + + patch_pos_embed = patch_pos_embed.permute(0, 2, 3, 1).view(1, -1, dim) + return patch_pos_embed + + def forward(self, pixel_values: torch.FloatTensor, interpolate_pos_encoding=False) -> torch.Tensor: + _, _, height, width = pixel_values.shape + target_dtype = self.patch_embedding.weight.dtype + patch_embeds = self.patch_embedding(pixel_values.to(dtype=target_dtype)) # shape = [*, width, grid, grid] + embeddings = patch_embeds.flatten(2).transpose(1, 2) + + if interpolate_pos_encoding: + embeddings = embeddings + self.interpolate_pos_encoding(embeddings, height, width) + else: + embeddings = embeddings + self.position_embedding(self.position_ids) + return embeddings + + +# Copied from transformers.models.clip.modeling_clip.CLIPTextEmbeddings with CLIP->Siglip +class SiglipTextEmbeddings(nn.Module): + def __init__(self, config: SiglipTextConfig): + super().__init__() + embed_dim = config.hidden_size + + self.token_embedding = nn.Embedding(config.vocab_size, embed_dim) + self.position_embedding = nn.Embedding(config.max_position_embeddings, embed_dim) + + # position_ids (1, len position emb) is contiguous in memory and exported when serialized + self.register_buffer( + "position_ids", torch.arange(config.max_position_embeddings).expand((1, -1)), persistent=False + ) + + def forward( + self, + input_ids: torch.LongTensor | None = None, + position_ids: torch.LongTensor | None = None, + inputs_embeds: torch.FloatTensor | None = None, + ) -> torch.Tensor: + seq_length = input_ids.shape[-1] if input_ids is not None else inputs_embeds.shape[-2] + max_position_embedding = self.position_embedding.weight.shape[0] + + if seq_length > max_position_embedding: + raise ValueError( + f"Sequence length must be less than max_position_embeddings (got `sequence length`: " + f"{seq_length} and max_position_embeddings: {max_position_embedding}" + ) + + if position_ids is None: + position_ids = self.position_ids[:, :seq_length] + + if inputs_embeds is None: + inputs_embeds = self.token_embedding(input_ids) + + position_embeddings = self.position_embedding(position_ids) + embeddings = inputs_embeds + position_embeddings + + return embeddings + + +def eager_attention_forward( + module: nn.Module, + query: torch.Tensor, + key: torch.Tensor, + value: torch.Tensor, + attention_mask: torch.Tensor | None, + scaling: float, + dropout: float = 0.0, + **kwargs, +): + attn_weights = torch.matmul(query, key.transpose(-1, -2)) * scaling + if attention_mask is not None: + attn_weights = attn_weights + attention_mask + + attn_weights = nn.functional.softmax(attn_weights, dim=-1, dtype=torch.float32).to(query.dtype) + attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training) + + attn_output = torch.matmul(attn_weights, value) + attn_output = attn_output.transpose(1, 2).contiguous() + + return attn_output, attn_weights + + +class SiglipAttention(nn.Module): + """Multi-headed attention from 'Attention Is All You Need' paper""" + + def __init__(self, config): + super().__init__() + self.config = config + self.embed_dim = config.hidden_size + self.num_heads = config.num_attention_heads + self.head_dim = self.embed_dim // self.num_heads + if self.head_dim * self.num_heads != self.embed_dim: + raise ValueError( + f"embed_dim must be divisible by num_heads (got `embed_dim`: {self.embed_dim} and `num_heads`:" + f" {self.num_heads})." + ) + self.scale = self.head_dim**-0.5 + self.dropout = config.attention_dropout + self.is_causal = False + + self.k_proj = nn.Linear(self.embed_dim, self.embed_dim) + self.v_proj = nn.Linear(self.embed_dim, self.embed_dim) + self.q_proj = nn.Linear(self.embed_dim, self.embed_dim) + self.out_proj = nn.Linear(self.embed_dim, self.embed_dim) + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.Tensor | None = None, + **kwargs, + ) -> tuple[torch.Tensor, torch.Tensor | None]: + """Input shape: Batch x Time x Channel""" + + batch_size, seq_length, embed_dim = hidden_states.shape + + queries = self.q_proj(hidden_states) + keys = self.k_proj(hidden_states) + values = self.v_proj(hidden_states) + + queries = queries.view(batch_size, seq_length, self.num_heads, self.head_dim).transpose(1, 2) + keys = keys.view(batch_size, seq_length, self.num_heads, self.head_dim).transpose(1, 2) + values = values.view(batch_size, seq_length, self.num_heads, self.head_dim).transpose(1, 2) + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, eager_attention_forward + ) + + attn_output, attn_weights = attention_interface( + self, + queries, + keys, + values, + attention_mask, + is_causal=self.is_causal, + scaling=self.scale, + dropout=0.0 if not self.training else self.dropout, + ) + + attn_output = attn_output.reshape(batch_size, seq_length, embed_dim).contiguous() + attn_output = self.out_proj(attn_output) + + return attn_output, attn_weights + + +# Copied from transformers.models.clip.modeling_clip.CLIPMLP with CLIP->Siglip +class SiglipMLP(nn.Module): + def __init__(self, config): + super().__init__() + self.config = config + self.activation_fn = ACT2FN[config.hidden_act] + self.fc1 = nn.Linear(config.hidden_size, config.intermediate_size) + self.fc2 = nn.Linear(config.intermediate_size, config.hidden_size) + + def forward(self, hidden_states: torch.Tensor) -> torch.Tensor: + hidden_states = self.fc1(hidden_states) + hidden_states = self.activation_fn(hidden_states) + hidden_states = self.fc2(hidden_states) + return hidden_states + + +class SiglipEncoderLayer(GradientCheckpointingLayer): + def __init__(self, config: SiglipVisionConfig | SiglipTextConfig): + super().__init__() + self.embed_dim = config.hidden_size + self.layer_norm1 = nn.LayerNorm(self.embed_dim, eps=config.layer_norm_eps) + self.self_attn = SiglipAttention(config) + self.layer_norm2 = nn.LayerNorm(self.embed_dim, eps=config.layer_norm_eps) + self.mlp = SiglipMLP(config) + + @auto_docstring + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.Tensor, + **kwargs: Unpack[TransformersKwargs], + ) -> torch.FloatTensor: + residual = hidden_states + + hidden_states = self.layer_norm1(hidden_states) + hidden_states, _ = self.self_attn( + hidden_states=hidden_states, + attention_mask=attention_mask, + **kwargs, + ) + hidden_states = residual + hidden_states + + residual = hidden_states + hidden_states = self.layer_norm2(hidden_states) + hidden_states = self.mlp(hidden_states) + hidden_states = residual + hidden_states + + return hidden_states + + +@auto_docstring +class SiglipPreTrainedModel(PreTrainedModel): + config: SiglipConfig + base_model_prefix = "siglip" + input_modalities = ("image", "text") + supports_gradient_checkpointing = True + + _no_split_modules = [ + "SiglipTextEmbeddings", + "SiglipVisionEmbeddings", + "SiglipEncoderLayer", + "SiglipMultiheadAttentionPoolingHead", + ] + _supports_flash_attn = True + _supports_sdpa = True + _supports_flex_attn = True + _supports_attention_backend = True + + _can_record_outputs = { + "hidden_states": SiglipEncoderLayer, + "attentions": SiglipAttention, + } + + @torch.no_grad() + def _init_weights(self, module): + """Initialize the weights""" + if isinstance(module, SiglipVisionEmbeddings): + width = ( + self.config.vision_config.hidden_size + if isinstance(self.config, SiglipConfig) + else self.config.hidden_size + ) + init.normal_(module.position_embedding.weight, std=1 / np.sqrt(width)) + if hasattr(module, "position_ids"): + init.copy_(module.position_ids, torch.arange(module.position_ids.shape[-1]).expand((1, -1))) + elif isinstance(module, nn.Embedding): + init.default_flax_embed_init_(module.weight) + elif isinstance(module, SiglipAttention): + init.xavier_uniform_(module.q_proj.weight) + init.xavier_uniform_(module.k_proj.weight) + init.xavier_uniform_(module.v_proj.weight) + init.xavier_uniform_(module.out_proj.weight) + init.zeros_(module.q_proj.bias) + init.zeros_(module.k_proj.bias) + init.zeros_(module.v_proj.bias) + init.zeros_(module.out_proj.bias) + elif isinstance(module, SiglipMLP): + init.xavier_uniform_(module.fc1.weight) + init.xavier_uniform_(module.fc2.weight) + init.normal_(module.fc1.bias, std=1e-6) + init.normal_(module.fc2.bias, std=1e-6) + elif isinstance(module, SiglipMultiheadAttentionPoolingHead): + init.xavier_uniform_(module.probe) + init.xavier_uniform_(module.attention.in_proj_weight) + init.zeros_(module.attention.in_proj_bias) + elif isinstance(module, SiglipModel): + init.zeros_(module.logit_scale) + init.zeros_(module.logit_bias) + elif isinstance(module, SiglipForImageClassification): + init.normal_( + module.classifier.weight, + std=self.config.vision_config.hidden_size**-0.5 * self.config.initializer_factor, + ) + elif isinstance(module, (nn.Linear, nn.Conv2d)): + init.lecun_normal_(module.weight) + if module.bias is not None: + init.zeros_(module.bias) + elif isinstance(module, nn.LayerNorm): + init.zeros_(module.bias) + init.ones_(module.weight) + elif isinstance(module, SiglipTextEmbeddings): + init.copy_(module.position_ids, torch.arange(module.position_ids.shape[-1]).expand((1, -1))) + + +# Copied from transformers.models.altclip.modeling_altclip.AltCLIPEncoder with AltCLIP->Siglip +class SiglipEncoder(nn.Module): + """ + Transformer encoder consisting of `config.num_hidden_layers` self attention layers. Each layer is a + [`SiglipEncoderLayer`]. + + Args: + config: SiglipConfig + """ + + def __init__(self, config: SiglipConfig): + super().__init__() + self.config = config + self.layers = nn.ModuleList([SiglipEncoderLayer(config) for _ in range(config.num_hidden_layers)]) + self.gradient_checkpointing = False + + # Ignore copy + @auto_docstring + def forward( + self, + inputs_embeds, + attention_mask: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> BaseModelOutput: + hidden_states = inputs_embeds + for encoder_layer in self.layers: + hidden_states = encoder_layer( + hidden_states, + attention_mask, + **kwargs, + ) + + return BaseModelOutput(last_hidden_state=hidden_states) + + +class SiglipTextTransformer(SiglipPreTrainedModel): + _input_embed_layer = "token_embedding" + + def __init__(self, config: SiglipTextConfig): + super().__init__(config) + self.config = config + embed_dim = config.hidden_size + self.embeddings = SiglipTextEmbeddings(config) + self.encoder = SiglipEncoder(config) + self.final_layer_norm = nn.LayerNorm(embed_dim, eps=config.layer_norm_eps) + + self.head = nn.Linear(embed_dim, config.projection_size) + self.post_init() + + @can_return_tuple + @auto_docstring + def forward( + self, + input_ids: torch.Tensor | None = None, + attention_mask: torch.Tensor | None = None, + position_ids: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> BaseModelOutputWithPooling: + if input_ids is None: + raise ValueError("You have to specify input_ids") + + input_shape = input_ids.size() + input_ids = input_ids.view(-1, input_shape[-1]) + + hidden_states = self.embeddings(input_ids=input_ids, position_ids=position_ids) + + # note: SigLIP's text model does not use a causal mask, unlike the original CLIP model. + attention_mask = create_bidirectional_mask( + config=self.config, + inputs_embeds=hidden_states, + attention_mask=attention_mask, + ) + + encoder_outputs: BaseModelOutput = self.encoder( + inputs_embeds=hidden_states, + attention_mask=attention_mask, + **kwargs, + ) + + last_hidden_state = encoder_outputs.last_hidden_state + last_hidden_state = self.final_layer_norm(last_hidden_state) + + # The model uses the last token's hidden state, which may be padding. + pooled_output = last_hidden_state[:, -1, :] + pooled_output = self.head(pooled_output) + + return BaseModelOutputWithPooling( + last_hidden_state=last_hidden_state, + pooler_output=pooled_output, + ) + + +@auto_docstring( + custom_intro=""" + The text model from SigLIP without any head or projection on top. + """ +) +class SiglipTextModel(SiglipPreTrainedModel): + config: SiglipTextConfig + input_modalities = ("text",) + + def __init__(self, config: SiglipTextConfig): + super().__init__(config) + self.text_model = SiglipTextTransformer(config) + # Initialize weights and apply final processing + self.post_init() + + def get_input_embeddings(self) -> nn.Module: + return self.text_model.embeddings.token_embedding + + def set_input_embeddings(self, value): + self.text_model.embeddings.token_embedding = value + + @merge_with_config_defaults + @capture_outputs(tie_last_hidden_states=False) + @auto_docstring + def forward( + self, + input_ids: torch.Tensor | None = None, + attention_mask: torch.Tensor | None = None, + position_ids: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> BaseModelOutputWithPooling: + r""" + Examples: + + ```python + >>> from transformers import AutoTokenizer, SiglipTextModel + + >>> model = SiglipTextModel.from_pretrained("google/siglip-base-patch16-224") + >>> tokenizer = AutoTokenizer.from_pretrained("google/siglip-base-patch16-224") + + >>> # important: make sure to set padding="max_length" as that's how the model was trained + >>> inputs = tokenizer(["a photo of a cat", "a photo of a dog"], padding="max_length", return_tensors="pt") + + >>> outputs = model(**inputs) + >>> last_hidden_state = outputs.last_hidden_state + >>> pooled_output = outputs.pooler_output # pooled (EOS token) states + ```""" + + return self.text_model( + input_ids=input_ids, + attention_mask=attention_mask, + position_ids=position_ids, + **kwargs, + ) + + +class SiglipVisionTransformer(SiglipPreTrainedModel): + _input_embed_layer = "patch_embedding" + + def __init__(self, config: SiglipVisionConfig): + super().__init__(config) + self.config = config + embed_dim = config.hidden_size + + self.embeddings = SiglipVisionEmbeddings(config) + self.encoder = SiglipEncoder(config) + self.post_layernorm = nn.LayerNorm(embed_dim, eps=config.layer_norm_eps) + self.use_head = True if not hasattr(config, "vision_use_head") else config.vision_use_head + if self.use_head: + self.head = SiglipMultiheadAttentionPoolingHead(config) + + self.post_init() + + @auto_docstring + def forward( + self, + pixel_values, + interpolate_pos_encoding: bool | None = False, + **kwargs: Unpack[TransformersKwargs], + ) -> BaseModelOutputWithPooling: + hidden_states = self.embeddings(pixel_values, interpolate_pos_encoding=interpolate_pos_encoding) + + encoder_outputs: BaseModelOutput = self.encoder( + inputs_embeds=hidden_states, + **kwargs, + ) + + last_hidden_state = encoder_outputs.last_hidden_state + last_hidden_state = self.post_layernorm(last_hidden_state) + + pooler_output = self.head(last_hidden_state) if self.use_head else None + + return BaseModelOutputWithPooling( + last_hidden_state=last_hidden_state, + pooler_output=pooler_output, + ) + + +class SiglipMultiheadAttentionPoolingHead(nn.Module): + """Multihead Attention Pooling.""" + + def __init__(self, config: SiglipVisionConfig): + super().__init__() + + self.probe = nn.Parameter(torch.randn(1, 1, config.hidden_size)) + self.attention = torch.nn.MultiheadAttention(config.hidden_size, config.num_attention_heads, batch_first=True) + self.layernorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps) + self.mlp = SiglipMLP(config) + + def forward(self, hidden_state): + batch_size = hidden_state.shape[0] + probe = self.probe.repeat(batch_size, 1, 1) + + hidden_state = self.attention(probe, hidden_state, hidden_state)[0] + + residual = hidden_state + hidden_state = self.layernorm(hidden_state) + hidden_state = residual + self.mlp(hidden_state) + + return hidden_state[:, 0] + + +@auto_docstring( + custom_intro=""" + The vision model from SigLIP without any head or projection on top. + """ +) +class SiglipVisionModel(SiglipPreTrainedModel): + config: SiglipVisionConfig + main_input_name = "pixel_values" + input_modalities = ("image",) + + def __init__(self, config: SiglipVisionConfig): + super().__init__(config) + + self.vision_model = SiglipVisionTransformer(config) + + # Initialize weights and apply final processing + self.post_init() + + def get_input_embeddings(self) -> nn.Module: + return self.vision_model.embeddings.patch_embedding + + @merge_with_config_defaults + @capture_outputs(tie_last_hidden_states=False) + @auto_docstring + def forward( + self, + pixel_values, + interpolate_pos_encoding: bool = False, + **kwargs: Unpack[TransformersKwargs], + ) -> BaseModelOutputWithPooling: + r""" + Examples: + + ```python + >>> from PIL import Image + >>> import httpx + >>> from io import BytesIO + >>> from transformers import AutoProcessor, SiglipVisionModel + + >>> model = SiglipVisionModel.from_pretrained("google/siglip-base-patch16-224") + >>> processor = AutoProcessor.from_pretrained("google/siglip-base-patch16-224") + + >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg" + >>> with httpx.stream("GET", url) as response: + ... image = Image.open(BytesIO(response.read())) + + >>> inputs = processor(images=image, return_tensors="pt") + + >>> outputs = model(**inputs) + >>> last_hidden_state = outputs.last_hidden_state + >>> pooled_output = outputs.pooler_output # pooled features + ```""" + + return self.vision_model( + pixel_values=pixel_values, + interpolate_pos_encoding=interpolate_pos_encoding, + **kwargs, + ) + + +@auto_docstring +class SiglipModel(SiglipPreTrainedModel): + config: SiglipConfig + + def __init__(self, config: SiglipConfig): + super().__init__(config) + + if not isinstance(config.text_config, SiglipTextConfig): + raise TypeError( + "config.text_config is expected to be of type SiglipTextConfig but is of type" + f" {type(config.text_config)}." + ) + + if not isinstance(config.vision_config, SiglipVisionConfig): + raise TypeError( + "config.vision_config is expected to be of type SiglipVisionConfig but is of type" + f" {type(config.vision_config)}." + ) + + text_config = config.text_config + vision_config = config.vision_config + + # First, initialize the text and vision models with proper attention implementation + text_model = SiglipTextModel._from_config(text_config) + vision_model = SiglipVisionModel._from_config(vision_config) + + # Second, get the text and vision submodules (for backward compatibility) + self.text_model = text_model.text_model + self.vision_model = vision_model.vision_model + + self.logit_scale = nn.Parameter(torch.randn(1)) + self.logit_bias = nn.Parameter(torch.randn(1)) + + # Initialize weights and apply final processing + self.post_init() + + def get_input_embeddings(self) -> nn.Module: + return self.text_model.embeddings.token_embedding + + def set_input_embeddings(self, value: nn.Module): + self.text_model.embeddings.token_embedding = value + + @can_return_tuple + @auto_docstring + def get_text_features( + self, + input_ids: torch.Tensor, + attention_mask: torch.Tensor | None = None, + position_ids: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple | BaseModelOutputWithPooling: + r""" + Examples: + + ```python + >>> from transformers import AutoTokenizer, AutoModel + >>> import torch + + >>> model = AutoModel.from_pretrained("google/siglip-base-patch16-224") + >>> tokenizer = AutoTokenizer.from_pretrained("google/siglip-base-patch16-224") + + >>> # important: make sure to set padding="max_length" as that's how the model was trained + >>> inputs = tokenizer(["a photo of a cat", "a photo of a dog"], padding="max_length", return_tensors="pt") + >>> with torch.no_grad(): + ... text_features = model.get_text_features(**inputs) + ```""" + return self.text_model( + input_ids=input_ids, + attention_mask=attention_mask, + position_ids=position_ids, + **kwargs, + ) + + @can_return_tuple + @auto_docstring + def get_image_features( + self, + pixel_values: torch.FloatTensor, + interpolate_pos_encoding: bool = False, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple | BaseModelOutputWithPooling: + r""" + Examples: + + ```python + >>> import torch + >>> from transformers import AutoProcessor, AutoModel + >>> from transformers.image_utils import load_image + + >>> model = AutoModel.from_pretrained("google/siglip-base-patch16-224") + >>> processor = AutoProcessor.from_pretrained("google/siglip-base-patch16-224") + + >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg" + >>> image = load_image(url) + + >>> inputs = processor(images=image, return_tensors="pt") + + >>> with torch.no_grad(): + ... image_features = model.get_image_features(**inputs) + ```""" + return self.vision_model( + pixel_values=pixel_values, + interpolate_pos_encoding=interpolate_pos_encoding, + **kwargs, + ) + + # NOTE: SiglipModel uses Pretrained backbones, so we don't need to add `capture_outputs` here + @can_return_tuple + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + pixel_values: torch.FloatTensor | None = None, + attention_mask: torch.Tensor | None = None, + position_ids: torch.LongTensor | None = None, + return_loss: bool | None = None, + interpolate_pos_encoding: bool = False, + **kwargs: Unpack[TransformersKwargs], + ) -> SiglipOutput: + r""" + return_loss (`bool`, *optional*): + Whether or not to return the contrastive loss. + + Examples: + + ```python + >>> from PIL import Image + >>> import httpx + >>> from io import BytesIO + >>> from transformers import AutoProcessor, AutoModel + >>> import torch + + >>> model = AutoModel.from_pretrained("google/siglip-base-patch16-224") + >>> processor = AutoProcessor.from_pretrained("google/siglip-base-patch16-224") + + >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg" + >>> with httpx.stream("GET", url) as response: + ... image = Image.open(BytesIO(response.read())) + + >>> texts = ["a photo of 2 cats", "a photo of 2 dogs"] + >>> # important: we pass `padding=max_length` since the model was trained with this + >>> inputs = processor(text=texts, images=image, padding="max_length", return_tensors="pt") + + >>> with torch.no_grad(): + ... outputs = model(**inputs) + + >>> logits_per_image = outputs.logits_per_image + >>> probs = torch.sigmoid(logits_per_image) # these are the probabilities + >>> print(f"{probs[0][0]:.1%} that image 0 is '{texts[0]}'") + 31.9% that image 0 is 'a photo of 2 cats' + ```""" + vision_outputs: BaseModelOutputWithPooling = self.vision_model( + pixel_values=pixel_values, + interpolate_pos_encoding=interpolate_pos_encoding, + **kwargs, + ) + + text_outputs: BaseModelOutputWithPooling = self.text_model( + input_ids=input_ids, + attention_mask=attention_mask, + position_ids=position_ids, + **kwargs, + ) + + image_embeds = vision_outputs.pooler_output + text_embeds = text_outputs.pooler_output + + # normalized features + image_embeds = image_embeds / image_embeds.norm(p=2, dim=-1, keepdim=True) + text_embeds = text_embeds / text_embeds.norm(p=2, dim=-1, keepdim=True) + + # cosine similarity as logits + logits_per_text = torch.matmul(text_embeds, image_embeds.t().to(text_embeds.device)) + + logit_scale, logit_bias = self.logit_scale.to(text_embeds.device), self.logit_bias.to(text_embeds.device) + logits_per_text = logits_per_text * logit_scale.exp() + logit_bias + + logits_per_image = logits_per_text.t() + + loss = None + if return_loss: + # Adapted from https://github.com/google-research/big_vision/blob/01edb81a4716f93a48be43b3a4af14e29cdb3a7f/big_vision/trainers/proj/image_text/siglip.py#L287 + eye = torch.eye(logits_per_text.size(0), device=logits_per_text.device) + m1_diag1 = -torch.ones_like(logits_per_text) + 2 * eye + loglik = torch.nn.functional.logsigmoid(m1_diag1 * logits_per_text) + nll = -torch.sum(loglik, dim=-1) + loss = nll.mean() + + return SiglipOutput( + loss=loss, + logits_per_image=logits_per_image, + logits_per_text=logits_per_text, + text_embeds=text_embeds, + image_embeds=image_embeds, + text_model_output=text_outputs, + vision_model_output=vision_outputs, + ) + + +@auto_docstring( + custom_intro=""" + SigLIP vision encoder with an image classification head on top (a linear layer on top of the pooled final hidden states of + the patch tokens) e.g. for ImageNet. + """ +) +class SiglipForImageClassification(SiglipPreTrainedModel): + main_input_name = "pixel_values" + input_modalities = ("image",) + + def __init__(self, config: SiglipConfig) -> None: + super().__init__(config) + + self.num_labels = config.num_labels + + # Create the vision model with proper attention + # and take only vision_model submodule (for backward compatibility) + vision_model = SiglipVisionModel._from_config(config.vision_config) + self.vision_model = vision_model.vision_model + + # Classifier head + self.classifier = ( + nn.Linear(config.vision_config.hidden_size, config.num_labels) if config.num_labels > 0 else nn.Identity() + ) + + # Initialize weights and apply final processing + self.post_init() + + def get_input_embeddings(self) -> nn.Module: + return self.vision_model.embeddings.patch_embedding + + def set_input_embeddings(self, value: nn.Module): + self.vision_model.embeddings.patch_embedding = value + + @merge_with_config_defaults + @capture_outputs + @auto_docstring + def forward( + self, + pixel_values: torch.Tensor | None = None, + labels: torch.Tensor | None = None, + interpolate_pos_encoding: bool = False, + **kwargs: Unpack[TransformersKwargs], + ) -> ImageClassifierOutput: + r""" + labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*): + Labels for computing the image classification/regression loss. Indices should be in `[0, ..., + config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If + `config.num_labels > 1` a classification loss is computed (Cross-Entropy). + + Examples: + + ```python + >>> from transformers import AutoImageProcessor, SiglipForImageClassification + >>> import torch + >>> from PIL import Image + >>> import httpx + >>> from io import BytesIO + + >>> torch.manual_seed(3) # doctest: +IGNORE_RESULT + >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg" + >>> with httpx.stream("GET", url) as response: + ... image = Image.open(BytesIO(response.read())) + + >>> # note: we are loading a `SiglipModel` from the hub here, + >>> # so the head will be randomly initialized, hence the predictions will be random if seed is not set above. + >>> image_processor = AutoImageProcessor.from_pretrained("google/siglip-base-patch16-224") + >>> model = SiglipForImageClassification.from_pretrained("google/siglip-base-patch16-224") + + >>> inputs = image_processor(images=image, return_tensors="pt") + >>> outputs = model(**inputs) + >>> logits = outputs.logits + >>> # model predicts one of the two classes + >>> predicted_class_idx = logits.argmax(-1).item() + >>> print("Predicted class:", model.config.id2label[predicted_class_idx]) + Predicted class: LABEL_1 + ```""" + outputs: BaseModelOutputWithPooling = self.vision_model( + pixel_values, + interpolate_pos_encoding=interpolate_pos_encoding, + **kwargs, + ) + + sequence_output = outputs.last_hidden_state + + # average pool the patch tokens + sequence_output = torch.mean(sequence_output, dim=1) + # apply classifier + logits = self.classifier(sequence_output) + + loss = None + if labels is not None: + loss = self.loss_function(labels, logits, self.config) + + return ImageClassifierOutput( + loss=loss, + logits=logits, + ) + + +__all__ = [ + "SiglipModel", + "SiglipPreTrainedModel", + "SiglipTextModel", + "SiglipVisionModel", + "SiglipForImageClassification", +] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/siglip/processing_siglip.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/siglip/processing_siglip.py new file mode 100644 index 0000000000000000000000000000000000000000..0e554b22ce3241a056880faece92515460b63c81 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/siglip/processing_siglip.py @@ -0,0 +1,28 @@ +# Copyright 2024 The HuggingFace Inc. team. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +""" +Image/Text processor class for SigLIP. +""" + +from ...processing_utils import ProcessorMixin +from ...utils import auto_docstring + + +@auto_docstring +class SiglipProcessor(ProcessorMixin): + def __init__(self, image_processor, tokenizer): + super().__init__(image_processor, tokenizer) + + +__all__ = ["SiglipProcessor"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/siglip/tokenization_siglip.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/siglip/tokenization_siglip.py new file mode 100644 index 0000000000000000000000000000000000000000..001da7cbb6175b7183e9c2284db02f3c9cbc7bb0 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/siglip/tokenization_siglip.py @@ -0,0 +1,352 @@ +# Copyright 2024 The HuggingFace Inc. team. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""Tokenization class for SigLIP model.""" + +import os +import re +import string +import warnings +from shutil import copyfile +from typing import TYPE_CHECKING, Any + +import sentencepiece as spm + +from ...tokenization_utils_base import AddedToken +from ...tokenization_utils_sentencepiece import SentencePieceBackend + + +if TYPE_CHECKING: + from ...tokenization_utils_base import TextInput +from ...utils import logging, requires_backends +from ...utils.import_utils import requires + + +logger = logging.get_logger(__name__) + +VOCAB_FILES_NAMES = {"vocab_file": "spiece.model"} + + +SPIECE_UNDERLINE = "▁" + + +@requires(backends=("sentencepiece",)) +class SiglipTokenizer(SentencePieceBackend): + """ + Construct a Siglip tokenizer. Based on [SentencePiece](https://github.com/google/sentencepiece). + + This tokenizer inherits from [`PreTrainedTokenizer`] which contains most of the main methods. Users should refer to + this superclass for more information regarding those methods. + + Args: + vocab_file (`str`): + [SentencePiece](https://github.com/google/sentencepiece) file (generally has a *.spm* extension) that + contains the vocabulary necessary to instantiate a tokenizer. + eos_token (`str`, *optional*, defaults to `""`): + The end of sequence token. + unk_token (`str`, *optional*, defaults to `""`): + The unknown token. A token that is not in the vocabulary cannot be converted to an ID and is set to be this + token instead. + pad_token (`str`, *optional*, defaults to `""`): + The token used for padding, for example when batching sequences of different lengths. + additional_special_tokens (`list[str]`, *optional*): + Additional special tokens used by the tokenizer. + sp_model_kwargs (`dict`, *optional*): + Will be passed to the `SentencePieceProcessor.__init__()` method. The [Python wrapper for + SentencePiece](https://github.com/google/sentencepiece/tree/master/python) can be used, among other things, + to set: + + - `enable_sampling`: Enable subword regularization. + - `nbest_size`: Sampling parameters for unigram. Invalid for BPE-Dropout. + + - `nbest_size = {0,1}`: No sampling is performed. + - `nbest_size > 1`: samples from the nbest_size results. + - `nbest_size < 0`: assuming that nbest_size is infinite and samples from the all hypothesis (lattice) + using forward-filtering-and-backward-sampling algorithm. + + - `alpha`: Smoothing parameter for unigram sampling, and dropout probability of merge operations for + BPE-dropout. + model_max_length (`int`, *optional*, defaults to 64): + The maximum length (in number of tokens) for model inputs. + do_lower_case (`bool`, *optional*, defaults to `True`): + Whether or not to lowercase the input when tokenizing. + """ + + vocab_files_names = VOCAB_FILES_NAMES + model_input_names = ["input_ids", "attention_mask"] + + def __init__( + self, + vocab_file, + eos_token="", + unk_token="", + pad_token="", + additional_special_tokens=None, + sp_model_kwargs: dict[str, Any] | None = None, + model_max_length=64, + do_lower_case=True, + **kwargs, + ) -> None: + requires_backends(self, "protobuf") + + pad_token = ( + AddedToken(pad_token, rstrip=True, lstrip=True, normalized=False, special=True) + if isinstance(pad_token, str) + else pad_token + ) + unk_token = ( + AddedToken(unk_token, rstrip=True, lstrip=True, normalized=False, special=True) + if isinstance(unk_token, str) + else unk_token + ) + eos_token = ( + AddedToken(eos_token, rstrip=True, lstrip=True, normalized=False, special=True) + if isinstance(eos_token, str) + else eos_token + ) + + self.sp_model_kwargs = {} if sp_model_kwargs is None else sp_model_kwargs + self.do_lower_case = do_lower_case + + super().__init__( + vocab_file=vocab_file, + eos_token=eos_token, + unk_token=unk_token, + pad_token=pad_token, + additional_special_tokens=additional_special_tokens, + sp_model_kwargs=self.sp_model_kwargs, + model_max_length=model_max_length, + do_lower_case=do_lower_case, + **kwargs, + ) + + @property + def vocab_size(self): + return self.sp_model.get_piece_size() + + def get_vocab(self): + vocab = {self.convert_ids_to_tokens(i): i for i in range(self.vocab_size)} + vocab.update(self.added_tokens_encoder) + return vocab + + def get_special_tokens_mask( + self, token_ids_0: list[int], token_ids_1: list[int] | None = None, already_has_special_tokens: bool = False + ) -> list[int]: + """ + Retrieve sequence ids from a token list that has no special tokens added. This method is called when adding + special tokens using the tokenizer `prepare_for_model` method. + + Args: + token_ids_0 (`list[int]`): + List of IDs. + token_ids_1 (`list[int]`, *optional*): + Optional second list of IDs for sequence pairs. + already_has_special_tokens (`bool`, *optional*, defaults to `False`): + Whether or not the token list is already formatted with special tokens for the model. + + Returns: + `list[int]`: A list of integers in the range [0, 1]: 1 for a special token, 0 for a sequence token. + """ + if already_has_special_tokens: + return super().get_special_tokens_mask( + token_ids_0=token_ids_0, token_ids_1=token_ids_1, already_has_special_tokens=True + ) + + # normal case: some special tokens + if token_ids_1 is None: + return ([0] * len(token_ids_0)) + [1] + return ([0] * len(token_ids_0)) + [1] + ([0] * len(token_ids_1)) + [1] + + def _add_eos_if_not_present(self, token_ids: list[int]) -> list[int]: + """Do not add eos again if user already added it.""" + if len(token_ids) > 0 and token_ids[-1] == self.eos_token_id: + warnings.warn( + f"This sequence already has {self.eos_token}. In future versions this behavior may lead to duplicated" + " eos tokens being added." + ) + return token_ids + else: + return token_ids + [self.eos_token_id] + + def create_token_type_ids_from_sequences( + self, token_ids_0: list[int], token_ids_1: list[int] | None = None + ) -> list[int]: + """ + Create a mask from the two sequences passed to be used in a sequence-pair classification task. T5 does not make + use of token type ids, therefore a list of zeros is returned. + + Args: + token_ids_0 (`list[int]`): + List of IDs. + token_ids_1 (`list[int]`, *optional*): + Optional second list of IDs for sequence pairs. + + Returns: + `list[int]`: List of zeros. + """ + eos = [self.eos_token_id] + + if token_ids_1 is None: + return len(token_ids_0 + eos) * [0] + return len(token_ids_0 + eos + token_ids_1 + eos) * [0] + + def build_inputs_with_special_tokens( + self, token_ids_0: list[int], token_ids_1: list[int] | None = None + ) -> list[int]: + """ + Build model inputs from a sequence or a pair of sequence for sequence classification tasks by concatenating and + adding special tokens. A sequence has the following format: + + - single sequence: `X ` + - pair of sequences: `A B ` + + Args: + token_ids_0 (`list[int]`): + List of IDs to which the special tokens will be added. + token_ids_1 (`list[int]`, *optional*): + Optional second list of IDs for sequence pairs. + + Returns: + `list[int]`: List of [input IDs](../glossary#input-ids) with the appropriate special tokens. + """ + token_ids_0 = self._add_eos_if_not_present(token_ids_0) + if token_ids_1 is None: + return token_ids_0 + else: + token_ids_1 = self._add_eos_if_not_present(token_ids_1) + return token_ids_0 + token_ids_1 + + def __getstate__(self): + state = self.__dict__.copy() + state["sp_model"] = None + return state + + def __setstate__(self, d): + self.__dict__ = d + + # for backward compatibility + if not hasattr(self, "sp_model_kwargs"): + self.sp_model_kwargs = {} + + self.sp_model = spm.SentencePieceProcessor(**self.sp_model_kwargs) + self.sp_model.Load(self.vocab_file) + + def remove_punctuation(self, text: str) -> str: + return text.translate(str.maketrans("", "", string.punctuation)) + + # source: https://github.com/google-research/big_vision/blob/3b8e5ab6ad4f96e32b32826f9e1b8fd277914f9c/big_vision/evaluators/proj/image_text/prompt_engineering.py#L94 + def canonicalize_text(self, text, *, keep_punctuation_exact_string=None): + """Returns canonicalized `text` (puncuation removed). + + Args: + text (`str`): + String to be canonicalized. + keep_punctuation_exact_string (`str`, *optional*): + If provided, then this exact string is kept. For example providing '{}' will keep any occurrences of '{}' + (but will still remove '{' and '}' that appear separately). + """ + if self.do_lower_case: + text = text.lower() + + if keep_punctuation_exact_string: + text = keep_punctuation_exact_string.join( + self.remove_punctuation(part) for part in text.split(keep_punctuation_exact_string) + ) + else: + text = self.remove_punctuation(text) + text = re.sub(r"\s+", " ", text) + text = text.strip() + + return text + + def tokenize(self, text: "TextInput", add_special_tokens=False, **kwargs) -> list[str]: + """ + Converts a string to a list of tokens. + """ + tokens = super().tokenize(SPIECE_UNDERLINE + text.replace(SPIECE_UNDERLINE, " "), **kwargs) + + if len(tokens) > 1 and tokens[0] == SPIECE_UNDERLINE and tokens[1] in self.all_special_tokens: + tokens = tokens[1:] + return tokens + + @property + def unk_token_length(self): + return len(self.sp_model.encode(str(self.unk_token))) + + def _tokenize(self, text, **kwargs): + """ + Returns a tokenized string. + + We de-activated the `add_dummy_prefix` option, thus the sentencepiece internals will always strip any + SPIECE_UNDERLINE. + + For example: `self.sp_model.encode(f"{SPIECE_UNDERLINE}Hey", out_type = str)` will give `['H', 'e', 'y']` instead of `['▁He', 'y']`. + + Thus we always encode `f"{unk_token}text"` and strip the `unk_token`. Here is an example with `unk_token = ""` and `unk_token_length = 4`. + `self.tokenizer.sp_model.encode(" Hey", out_type = str)[4:]`. + """ + text = self.canonicalize_text(text, keep_punctuation_exact_string=None) + tokens = self.sp_model.encode(text, out_type=str) + + # 1. Encode string + prefix ex: " Hey" + tokens = self.sp_model.encode(self.unk_token + text, out_type=str) + # 2. Remove self.unk_token from ['<','unk','>', '▁Hey'] + return tokens[self.unk_token_length :] if len(tokens) >= self.unk_token_length else tokens + + def _convert_token_to_id(self, token): + """Converts a token (str) in an id using the vocab.""" + return self.sp_model.piece_to_id(token) + + def _convert_id_to_token(self, index): + """Converts an index (integer) in a token (str) using the vocab.""" + token = self.sp_model.IdToPiece(index) + return token + + def convert_tokens_to_string(self, tokens): + """Converts a sequence of tokens (string) in a single string.""" + current_sub_tokens = [] + out_string = "" + prev_is_special = False + for token in tokens: + # make sure that special tokens are not decoded using sentencepiece model + if token in self.all_special_tokens: + if not prev_is_special: + out_string += " " + out_string += self.sp_model.decode(current_sub_tokens) + token + prev_is_special = True + current_sub_tokens = [] + else: + current_sub_tokens.append(token) + prev_is_special = False + out_string += self.sp_model.decode(current_sub_tokens) + return out_string.strip() + + def save_vocabulary(self, save_directory: str, filename_prefix: str | None = None) -> tuple[str]: + if not os.path.isdir(save_directory): + logger.error(f"Vocabulary path ({save_directory}) should be a directory") + return + out_vocab_file = os.path.join( + save_directory, (filename_prefix + "-" if filename_prefix else "") + VOCAB_FILES_NAMES["vocab_file"] + ) + + if os.path.abspath(self.vocab_file) != os.path.abspath(out_vocab_file) and os.path.isfile(self.vocab_file): + copyfile(self.vocab_file, out_vocab_file) + elif not os.path.isfile(self.vocab_file): + with open(out_vocab_file, "wb") as fi: + content_spiece_model = self.sp_model.serialized_model_proto() + fi.write(content_spiece_model) + + return (out_vocab_file,) + + +__all__ = ["SiglipTokenizer"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/siglip2/__init__.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/siglip2/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..54cd6e61d0e16a819fb608704906ada5f02c658b --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/siglip2/__init__.py @@ -0,0 +1,31 @@ +# Copyright 2025 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from typing import TYPE_CHECKING + +from ...utils import _LazyModule +from ...utils.import_utils import define_import_structure + + +if TYPE_CHECKING: + from .configuration_siglip2 import * + from .image_processing_siglip2 import * + from .image_processing_siglip2_fast import * + from .modeling_siglip2 import * + from .processing_siglip2 import * + from .tokenization_siglip2 import * +else: + import sys + + _file = globals()["__file__"] + sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__) diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/siglip2/configuration_siglip2.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/siglip2/configuration_siglip2.py new file mode 100644 index 0000000000000000000000000000000000000000..264f8c94fd001d0f62ae2934a5442a0d4dd9f2c3 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/siglip2/configuration_siglip2.py @@ -0,0 +1,270 @@ +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# This file was automatically generated from src/transformers/models/siglip2/modular_siglip2.py. +# Do NOT edit this file manually as any edits will be overwritten by the generation of +# the file from the modular. If any change should be done, please apply the change to the +# modular_siglip2.py file directly. One of our CI enforces this. +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# Copyright 2025 The HuggingFace Inc. team. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +from ...configuration_utils import PreTrainedConfig +from ...utils import logging + + +logger = logging.get_logger(__name__) + + +class Siglip2TextConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`Siglip2TextModel`]. It is used to instantiate a + Siglip2 text encoder according to the specified arguments, defining the model architecture. Instantiating a + configuration with the defaults will yield a similar configuration to that of the text encoder of the Siglip2 + [google/siglip2-base-patch16-224](https://huggingface.co/google/siglip2-base-patch16-224) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + vocab_size (`int`, *optional*, defaults to 32000): + Vocabulary size of the Siglip2 text model. Defines the number of different tokens that can be represented by + the `inputs_ids` passed when calling [`Siglip2Model`]. + hidden_size (`int`, *optional*, defaults to 768): + Dimensionality of the encoder layers and the pooler layer. + intermediate_size (`int`, *optional*, defaults to 3072): + Dimensionality of the "intermediate" (i.e., feed-forward) layer in the Transformer encoder. + num_hidden_layers (`int`, *optional*, defaults to 12): + Number of hidden layers in the Transformer encoder. + num_attention_heads (`int`, *optional*, defaults to 12): + Number of attention heads for each attention layer in the Transformer encoder. + max_position_embeddings (`int`, *optional*, defaults to 64): + The maximum sequence length that this model might ever be used with. Typically set this to something large + just in case (e.g., 512 or 1024 or 2048). + hidden_act (`str` or `function`, *optional*, defaults to `"gelu_pytorch_tanh"`): + The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`, + `"relu"`, `"selu"` and `"gelu_new"` `"quick_gelu"` are supported. + layer_norm_eps (`float`, *optional*, defaults to 1e-06): + The epsilon used by the layer normalization layers. + attention_dropout (`float`, *optional*, defaults to 0.0): + The dropout ratio for the attention probabilities. + pad_token_id (`int`, *optional*, defaults to 1): + The id of the padding token in the vocabulary. + bos_token_id (`int`, *optional*, defaults to 49406): + The id of the beginning-of-sequence token in the vocabulary. + eos_token_id (`int`, *optional*, defaults to 49407): + The id of the end-of-sequence token in the vocabulary. + projection_size (`int`, *optional*, defaults to `hidden_size`): + The size of the projection head. + + Example: + + ```python + >>> from transformers import Siglip2TextConfig, Siglip2TextModel + + >>> # Initializing a Siglip2TextConfig with google/siglip2-base-patch16-224 style configuration + >>> configuration = Siglip2TextConfig() + + >>> # Initializing a Siglip2TextModel (with random weights) from the google/siglip2-base-patch16-224 style configuration + >>> model = Siglip2TextModel(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "siglip2_text_model" + base_config_key = "text_config" + + def __init__( + self, + vocab_size=32000, + hidden_size=768, + intermediate_size=3072, + num_hidden_layers=12, + num_attention_heads=12, + max_position_embeddings=64, + hidden_act="gelu_pytorch_tanh", + layer_norm_eps=1e-6, + attention_dropout=0.0, + # This differs from `CLIPTokenizer`'s default and from openai/siglip2 + # See https://github.com/huggingface/transformers/pull/24773#issuecomment-1632287538 + pad_token_id=1, + bos_token_id=49406, + eos_token_id=49407, + projection_size=None, + **kwargs, + ): + super().__init__(**kwargs) + self.pad_token_id = pad_token_id + self.bos_token_id = bos_token_id + self.eos_token_id = eos_token_id + + self.vocab_size = vocab_size + self.hidden_size = hidden_size + self.intermediate_size = intermediate_size + self.num_hidden_layers = num_hidden_layers + self.num_attention_heads = num_attention_heads + self.max_position_embeddings = max_position_embeddings + self.layer_norm_eps = layer_norm_eps + self.hidden_act = hidden_act + self.attention_dropout = attention_dropout + self.projection_size = projection_size if projection_size is not None else hidden_size + + +class Siglip2VisionConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`Siglip2VisionModel`]. It is used to instantiate a + Siglip2 vision encoder according to the specified arguments, defining the model architecture. Instantiating a + configuration with the defaults will yield a similar configuration to that of the vision encoder of the Siglip2 + [google/siglip2-base-patch16-naflex](https://huggingface.co/google/siglip2-base-patch16-naflex) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + hidden_size (`int`, *optional*, defaults to 768): + Dimensionality of the encoder layers and the pooler layer. + intermediate_size (`int`, *optional*, defaults to 3072): + Dimensionality of the "intermediate" (i.e., feed-forward) layer in the Transformer encoder. + num_hidden_layers (`int`, *optional*, defaults to 12): + Number of hidden layers in the Transformer encoder. + num_attention_heads (`int`, *optional*, defaults to 12): + Number of attention heads for each attention layer in the Transformer encoder. + num_channels (`int`, *optional*, defaults to 3): + Number of channels in the input images. + num_patches (`int`, *optional*, defaults to 256): + The number of patches in the image with the size of (`patch_size`, `patch_size`). + The image is resized to fill maximum of this number of patches, and to preserve + the aspect ratio. In case the resulted number of patches is lower, the image is + padded in "patch" dimension. + patch_size (`int`, *optional*, defaults to 16): + The size (resolution) of each patch. + hidden_act (`str` or `function`, *optional*, defaults to `"gelu_pytorch_tanh"`): + The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`, + `"relu"`, `"selu"` and `"gelu_new"` `"quick_gelu"` are supported. + layer_norm_eps (`float`, *optional*, defaults to 1e-06): + The epsilon used by the layer normalization layers. + attention_dropout (`float`, *optional*, defaults to 0.0): + The dropout ratio for the attention probabilities. + + Example: + + ```python + >>> from transformers import Siglip2VisionConfig, Siglip2VisionModel + + >>> # Initializing a Siglip2VisionConfig with google/siglip2-base-patch16-naflex style configuration + >>> configuration = Siglip2VisionConfig() + + >>> # Initializing a Siglip2VisionModel (with random weights) from the google/siglip2-base-patch16-naflex style configuration + >>> model = Siglip2VisionModel(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "siglip2_vision_model" + base_config_key = "vision_config" + + def __init__( + self, + hidden_size=768, + intermediate_size=3072, + num_hidden_layers=12, + num_attention_heads=12, + num_channels=3, + num_patches=256, + patch_size=16, + hidden_act="gelu_pytorch_tanh", + layer_norm_eps=1e-6, + attention_dropout=0.0, + **kwargs, + ): + super().__init__(**kwargs) + + self.hidden_size = hidden_size + self.intermediate_size = intermediate_size + self.num_hidden_layers = num_hidden_layers + self.num_attention_heads = num_attention_heads + self.num_channels = num_channels + self.patch_size = patch_size + self.attention_dropout = attention_dropout + self.layer_norm_eps = layer_norm_eps + self.hidden_act = hidden_act + self.num_patches = num_patches + + +class Siglip2Config(PreTrainedConfig): + r""" + [`Siglip2Config`] is the configuration class to store the configuration of a [`Siglip2Model`]. It is used to + instantiate a Siglip2 model according to the specified arguments, defining the text model and vision model configs. + Instantiating a configuration with the defaults will yield a similar configuration to that of the Siglip2 + [google/siglip2-base-patch16-224](https://huggingface.co/google/siglip2-base-patch16-224) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + text_config (`dict`, *optional*): + Dictionary of configuration options used to initialize [`Siglip2TextConfig`]. + vision_config (`dict`, *optional*): + Dictionary of configuration options used to initialize [`Siglip2VisionConfig`]. + kwargs (*optional*): + Dictionary of keyword arguments. + + Example: + + ```python + >>> from transformers import Siglip2Config, Siglip2Model + + >>> # Initializing a Siglip2Config with google/siglip2-base-patch16-224 style configuration + >>> configuration = Siglip2Config() + + >>> # Initializing a Siglip2Model (with random weights) from the google/siglip2-base-patch16-224 style configuration + >>> model = Siglip2Model(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + + >>> # We can also initialize a Siglip2Config from a Siglip2TextConfig and a Siglip2VisionConfig + >>> from transformers import Siglip2TextConfig, Siglip2VisionConfig + + >>> # Initializing a Siglip2Text and Siglip2Vision configuration + >>> config_text = Siglip2TextConfig() + >>> config_vision = Siglip2VisionConfig() + + >>> config = Siglip2Config(text_config=config_text, vision_config=config_vision) + ```""" + + model_type = "siglip2" + sub_configs = {"text_config": Siglip2TextConfig, "vision_config": Siglip2VisionConfig} + + def __init__(self, text_config=None, vision_config=None, **kwargs): + if text_config is None: + text_config = Siglip2TextConfig() + logger.info("`text_config` is `None`. Initializing the `Siglip2TextConfig` with default values.") + elif isinstance(text_config, dict): + text_config = Siglip2TextConfig(**text_config) + + if vision_config is None: + vision_config = Siglip2VisionConfig() + logger.info("`vision_config` is `None`. initializing the `Siglip2VisionConfig` with default values.") + elif isinstance(vision_config, dict): + vision_config = Siglip2VisionConfig(**vision_config) + + self.text_config = text_config + self.vision_config = vision_config + self.initializer_factor = 1.0 + + super().__init__(**kwargs) + + +__all__ = ["Siglip2Config", "Siglip2TextConfig", "Siglip2VisionConfig"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/siglip2/image_processing_siglip2.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/siglip2/image_processing_siglip2.py new file mode 100644 index 0000000000000000000000000000000000000000..dd0daf87505029e870647362dd8db4d706f23432 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/siglip2/image_processing_siglip2.py @@ -0,0 +1,353 @@ +# Copyright 2025 The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""Image processor class for SigLIP2.""" + +import math +from functools import lru_cache +from typing import Optional + +import numpy as np + +from ...image_processing_utils import BaseImageProcessor, BatchFeature +from ...image_transforms import ( + convert_to_rgb, + resize, + to_channel_dimension_format, +) +from ...image_utils import ( + ChannelDimension, + ImageInput, + PILImageResampling, + infer_channel_dimension_format, + is_scaled_image, + make_flat_list_of_images, + to_numpy_array, + valid_images, + validate_preprocess_arguments, +) +from ...processing_utils import ImagesKwargs +from ...utils import TensorType, filter_out_non_signature_kwargs, is_vision_available, logging + + +logger = logging.get_logger(__name__) + + +if is_vision_available(): + from PIL import Image + + +class Siglip2ImageProcessorKwargs(ImagesKwargs, total=False): + """ + patch_size (`int`, *optional*, defaults to 16): + The size (resolution) of each patch the image will be split to. + max_num_patches (`int`, *optional*, defaults to 256): + The image will be resized to have at most this number of patches, + and then padded in "patch" dimension to match this number exactly. + """ + + patch_size: int + max_num_patches: int + + +@lru_cache(maxsize=256) +def get_image_size_for_max_num_patches( + image_height: int, image_width: int, patch_size: int, max_num_patches: int, eps: float = 1e-5 +) -> tuple[int, int]: + """ + Determine image size based on max number of patches, ensure dimensions are divisible by patch size and image is at least 1 patch. + + Args: + image_height (`int`): + Original image height. + image_width (`int`): + Original image width. + patch_size (`int`): + Patch size for processing. + max_num_patches (`int`): + Maximum number of patches. + eps (`float`): + Small threshold for binary search. + + Returns: + Tuple: (target_height, target_width) + """ + + def get_scaled_image_size(scale: float, size: int, patch_size: int) -> int: + scaled_size = size * scale + scaled_size = math.ceil(scaled_size / patch_size) * patch_size # make divisible by patch_size + scaled_size = max(patch_size, scaled_size) # ensure at least 1 patch + return int(scaled_size) + + # Binary search for optimal scale + scale_min, scale_max = eps / 10, 100.0 + while (scale_max - scale_min) >= eps: + scale = (scale_min + scale_max) / 2 + target_height = get_scaled_image_size(scale, image_height, patch_size) + target_width = get_scaled_image_size(scale, image_width, patch_size) + num_patches = (target_height / patch_size) * (target_width / patch_size) + + if num_patches <= max_num_patches: + scale_min = scale + else: + scale_max = scale + + scale = scale_min + target_height = get_scaled_image_size(scale, image_height, patch_size) + target_width = get_scaled_image_size(scale, image_width, patch_size) + return target_height, target_width + + +def convert_image_to_patches(image: np.ndarray, patch_size: int) -> np.ndarray: + """ + Convert 3D array image of shape (image_height, image_width, num_channels) into 2D array of patches of shape + (num_patches_height * num_patches_width, patch_size * patch_size * num_channels). + """ + image_height, image_width, num_channels = image.shape + num_patches_height = image_height // patch_size + num_patches_width = image_width // patch_size + patched_image = image.reshape(num_patches_height, patch_size, num_patches_width, patch_size, num_channels) + patched_image = patched_image.transpose(0, 2, 1, 3, 4) + patched_image = patched_image.reshape(num_patches_height * num_patches_width, -1) + return patched_image + + +def pad_along_first_dim(array: np.ndarray, target_length: int, pad_value: int = 0) -> tuple[np.ndarray, np.ndarray]: + """ + Pad the array along the first dimension. + """ + current_length = array.shape[0] + padding_length = target_length - current_length + mask = np.ones((target_length,), dtype=np.int32) + if padding_length > 0: + paddings = [(0, padding_length)] + [(0, 0)] * (array.ndim - 1) + array = np.pad(array, paddings, mode="constant", constant_values=pad_value) + mask[-padding_length:] = 0 + return array, mask + + +class Siglip2ImageProcessor(BaseImageProcessor): + r""" + Constructs a SigLIP2 image processor. + + Args: + do_resize (`bool`, *optional*, defaults to `True`): + Whether to resize the image's dimensions to fit `max_num_patches` according to given `patch_size`. + Can be overridden by `do_resize` in the `preprocess` method. + resample (`PILImageResampling`, *optional*, defaults to `Resampling.BILINEAR`): + Resampling filter to use if resizing the image. Can be overridden by `resample` in the `preprocess` method. + do_rescale (`bool`, *optional*, defaults to `True`): + Whether to rescale the image by the specified scale `rescale_factor`. Can be overridden by `do_rescale` in + the `preprocess` method. + rescale_factor (`int` or `float`, *optional*, defaults to `1/255`): + Scale factor to use if rescaling the image. Can be overridden by `rescale_factor` in the `preprocess` + method. + do_normalize (`bool`, *optional*, defaults to `True`): + Whether to normalize the image by the specified mean and standard deviation. Can be overridden by + `do_normalize` in the `preprocess` method. + image_mean (`float` or `list[float]`, *optional*, defaults to `[0.5, 0.5, 0.5]`): + Mean to use if normalizing the image. This is a float or list of floats the length of the number of + channels in the image. Can be overridden by the `image_mean` parameter in the `preprocess` method. + image_std (`float` or `list[float]`, *optional*, defaults to `[0.5, 0.5, 0.5]`): + Standard deviation to use if normalizing the image. This is a float or list of floats the length of the + number of channels in the image. Can be overridden by the `image_std` parameter in the `preprocess` method. + Can be overridden by the `image_std` parameter in the `preprocess` method. + do_convert_rgb (`bool`, *optional*, defaults to `True`): + Whether to convert the image to RGB. + patch_size (`int`, *optional*, defaults to 16): + The size (resolution) of each patch the image will be split to. + max_num_patches (`int`, *optional*, defaults to 256): + The image will be resized to have at most this number of patches, + and then padded in "patch" dimension to match this number exactly. + """ + + model_input_names = ["pixel_values", "pixel_attention_mask", "spatial_shapes"] + valid_kwargs = Siglip2ImageProcessorKwargs + + def __init__( + self, + do_resize: bool = True, + resample: "PILImageResampling" = PILImageResampling.BILINEAR, + do_rescale: bool = True, + rescale_factor: float = 1 / 255, + do_normalize: bool = True, + image_mean: float | list[float] | None = None, + image_std: float | list[float] | None = None, + do_convert_rgb: bool | None = None, + patch_size: int = 16, + max_num_patches: int = 256, + **kwargs, + ): + super().__init__(**kwargs) + + image_mean = image_mean if image_mean is not None else [0.5, 0.5, 0.5] + image_std = image_std if image_std is not None else [0.5, 0.5, 0.5] + + self.do_resize = do_resize + self.resample = resample + self.do_rescale = do_rescale + self.rescale_factor = rescale_factor + self.do_normalize = do_normalize + self.image_mean = image_mean + self.image_std = image_std + self.do_convert_rgb = do_convert_rgb + self.patch_size = patch_size + self.max_num_patches = max_num_patches + + @filter_out_non_signature_kwargs() + def preprocess( + self, + images: ImageInput, + do_resize: bool | None = None, + resample: Optional["PILImageResampling"] = None, + do_rescale: bool | None = None, + rescale_factor: float | None = None, + do_normalize: bool | None = None, + image_mean: float | list[float] | None = None, + image_std: float | list[float] | None = None, + return_tensors: str | TensorType | None = None, + input_data_format: str | ChannelDimension | None = None, + do_convert_rgb: bool | None = None, + patch_size: int | None = None, + max_num_patches: int | None = None, + ) -> "Image.Image": + """ + Preprocess an image or batch of images. + + Args: + images (`ImageInput`): + Image to preprocess. Expects a single or batch of images with pixel values ranging from 0 to 255. If + passing in images with pixel values between 0 and 1, set `do_rescale=False`. + do_resize (`bool`, *optional*, defaults to `self.do_resize`): + Whether to resize the image. + size (`dict[str, int]`, *optional*, defaults to `self.size`): + Size of the image after resizing. + resample (`int`, *optional*, defaults to `self.resample`): + Resampling filter to use if resizing the image. This can be one of the enum `PILImageResampling`. Only + has an effect if `do_resize` is set to `True`. + do_rescale (`bool`, *optional*, defaults to `self.do_rescale`): + Whether to rescale the image. + rescale_factor (`float`, *optional*, defaults to `self.rescale_factor`): + Rescale factor to rescale the image by if `do_rescale` is set to `True`. + do_normalize (`bool`, *optional*, defaults to `self.do_normalize`): + Whether to normalize the image. + image_mean (`float` or `list[float]`, *optional*, defaults to `self.image_mean`): + Image mean to use for normalization. Only has an effect if `do_normalize` is set to `True`. + image_std (`float` or `list[float]`, *optional*, defaults to `self.image_std`): + Image standard deviation to use for normalization. Only has an effect if `do_normalize` is set to + `True`. + return_tensors (`str` or `TensorType`, *optional*): + The type of tensors to return. Can be one of: + - Unset: Return a list of `np.ndarray`. + - `TensorType.PYTORCH` or `'pt'`: Return a batch of type `torch.Tensor`. + - `TensorType.NUMPY` or `'np'`: Return a batch of type `np.ndarray`. + input_data_format (`ChannelDimension` or `str`, *optional*): + The channel dimension format for the input image. If unset, the channel dimension format is inferred + from the input image. Can be one of: + - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format. + - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format. + - `"none"` or `ChannelDimension.NONE`: image in (height, width) format. + do_convert_rgb (`bool`, *optional*, defaults to `self.do_convert_rgb`): + Whether to convert the image to RGB. + patch_size (`int`, *optional*, defaults to `self.patch_size`): + Patch size for processing, same as the patch size used in the model. + max_num_patches (`int`, *optional*, defaults to `self.max_num_patches`): + Maximum number of patches per image, the image will be resized to have at most this number of patches. + """ + do_resize = do_resize if do_resize is not None else self.do_resize + resample = resample if resample is not None else self.resample + do_rescale = do_rescale if do_rescale is not None else self.do_rescale + rescale_factor = rescale_factor if rescale_factor is not None else self.rescale_factor + do_normalize = do_normalize if do_normalize is not None else self.do_normalize + image_mean = image_mean if image_mean is not None else self.image_mean + image_std = image_std if image_std is not None else self.image_std + do_convert_rgb = do_convert_rgb if do_convert_rgb is not None else self.do_convert_rgb + patch_size = patch_size if patch_size is not None else self.patch_size + max_num_patches = max_num_patches if max_num_patches is not None else self.max_num_patches + + # Explicitly specify data format to be channels last for image preprocessing. + # Image processor does not support different output formats, because it returns patches. + data_format = ChannelDimension.LAST + + images = self.fetch_images(images) + images = make_flat_list_of_images(images) + + if not valid_images(images): + raise ValueError("Invalid image type. Must be of type PIL.Image.Image, numpy.ndarray, or torch.Tensor") + validate_preprocess_arguments( + do_rescale=do_rescale, + rescale_factor=rescale_factor, + do_normalize=do_normalize, + image_mean=image_mean, + image_std=image_std, + ) + if do_convert_rgb: + images = [convert_to_rgb(image) for image in images] + + # All transformations expect numpy arrays. + images = [to_numpy_array(image) for image in images] + + if do_rescale and is_scaled_image(images[0]): + logger.warning_once( + "It looks like you are trying to rescale already rescaled images. If the input" + " images have pixel values between 0 and 1, set `do_rescale=False` to avoid rescaling them again." + ) + + if input_data_format is None: + # We assume that all images have the same channel dimension format. + input_data_format = infer_channel_dimension_format(images[0]) + + pixel_masks = [] + pixel_values = [] + spatial_shapes = [] + + for image in images: + image = to_channel_dimension_format(image, data_format, input_channel_dim=input_data_format) + + if do_resize: + height, width = get_image_size_for_max_num_patches( + image_height=image.shape[0], + image_width=image.shape[1], + patch_size=patch_size, + max_num_patches=max_num_patches, + ) + image = resize(image=image, size=(height, width), resample=resample, input_data_format=data_format) + + if do_rescale: + image = self.rescale(image=image, scale=rescale_factor, input_data_format=data_format) + + if do_normalize: + image = self.normalize(image=image, mean=image_mean, std=image_std, input_data_format=data_format) + + patches = convert_image_to_patches(image, patch_size) + patches, mask = pad_along_first_dim(patches, max_num_patches) + num_patches_height = image.shape[0] // patch_size + num_patches_width = image.shape[1] // patch_size + + spatial_shapes.append((num_patches_height, num_patches_width)) + pixel_values.append(patches) + pixel_masks.append(mask) + + batch_feature = BatchFeature( + data={ + "pixel_values": pixel_values, + "pixel_attention_mask": pixel_masks, + "spatial_shapes": spatial_shapes, + }, + tensor_type=return_tensors, + ) + + return batch_feature + + +__all__ = ["Siglip2ImageProcessor"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/siglip2/image_processing_siglip2_fast.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/siglip2/image_processing_siglip2_fast.py new file mode 100644 index 0000000000000000000000000000000000000000..de454d37a4a265bb0cc853f66e3f888faad1b9d8 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/siglip2/image_processing_siglip2_fast.py @@ -0,0 +1,148 @@ +# Copyright 2025 The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""Fast Image processor class for SigLIP2.""" + +from typing import Optional + +import torch +import torchvision.transforms.v2.functional as tvF + +from ...image_processing_utils import BatchFeature +from ...image_processing_utils_fast import BaseImageProcessorFast, SizeDict +from ...image_utils import ImageInput, PILImageResampling +from ...processing_utils import Unpack +from ...utils import ( + TensorType, + auto_docstring, + logging, +) +from .image_processing_siglip2 import Siglip2ImageProcessorKwargs, get_image_size_for_max_num_patches + + +logger = logging.get_logger(__name__) + + +def convert_image_to_patches(image: "torch.Tensor", patch_size: int) -> "torch.Tensor": + """ + Convert 3D tensor image of shape (num_channels, image_height, image_width) into 2D tensor of patches of shape + (num_patches_height * num_patches_width, patch_size * patch_size * num_channels). + """ + num_channels, image_height, image_width = image.shape + num_patches_height = image_height // patch_size + num_patches_width = image_width // patch_size + patched_image = image.reshape(num_channels, num_patches_height, patch_size, num_patches_width, patch_size) + patched_image = patched_image.permute(1, 3, 2, 4, 0) + patched_image = patched_image.reshape(num_patches_height * num_patches_width, -1) + return patched_image + + +def pad_along_first_dim( + tensor: "torch.Tensor", target_length: int, pad_value: int = 0 +) -> tuple["torch.Tensor", "torch.Tensor"]: + """ + Pad the tensor along the first dimension. + """ + current_length = tensor.shape[0] + padding_length = target_length - current_length + mask = torch.ones((target_length,), dtype=torch.int32) + if padding_length > 0: + padding = [0, 0] * (tensor.ndim - 1) + [0, padding_length] + tensor = torch.nn.functional.pad(tensor, padding, mode="constant", value=pad_value) + mask[-padding_length:] = 0 + return tensor, mask + + +@auto_docstring +class Siglip2ImageProcessorFast(BaseImageProcessorFast): + resample = PILImageResampling.BILINEAR + image_mean = [0.5, 0.5, 0.5] + image_std = [0.5, 0.5, 0.5] + do_resize = True + do_rescale = True + do_normalize = True + patch_size = 16 + max_num_patches = 256 + valid_kwargs = Siglip2ImageProcessorKwargs + + def __init__(self, **kwargs: Unpack[Siglip2ImageProcessorKwargs]): + super().__init__(**kwargs) + + def _validate_preprocess_kwargs(self, **kwargs) -> tuple: + # Remove do_resize from kwargs to not raise an error as size is None + kwargs.pop("do_resize", None) + return super()._validate_preprocess_kwargs(**kwargs) + + @auto_docstring + def preprocess(self, images: ImageInput, **kwargs: Unpack[Siglip2ImageProcessorKwargs]) -> BatchFeature: + return super().preprocess(images, **kwargs) + + def _preprocess( + self, + images: list["torch.Tensor"], + do_resize: bool, + patch_size: int, + max_num_patches: int, + interpolation: Optional["tvF.InterpolationMode"], + do_rescale: bool, + rescale_factor: float, + do_normalize: bool, + image_mean: float | list[float] | None, + image_std: float | list[float] | None, + return_tensors: str | TensorType | None, + **kwargs, + ) -> BatchFeature: + pixel_masks = [] + pixel_values = [] + spatial_shapes = [] + + for image in images: + if do_resize: + height, width = get_image_size_for_max_num_patches( + image_height=image.shape[1], + image_width=image.shape[2], + patch_size=patch_size, + max_num_patches=max_num_patches, + ) + size_dict = SizeDict(height=height, width=width) + image = self.resize(image=image, size=size_dict, interpolation=interpolation) + + image = self.rescale_and_normalize(image, do_rescale, rescale_factor, do_normalize, image_mean, image_std) + + # (num_channels, height, width) -> (num_patches, patch_size * patch_size * num_channels) + patches = convert_image_to_patches(image, patch_size) + patches, mask = pad_along_first_dim(patches, max_num_patches) + + num_patches_height = image.shape[1] // patch_size + num_patches_width = image.shape[2] // patch_size + + spatial_shapes.append((num_patches_height, num_patches_width)) + pixel_values.append(patches) + pixel_masks.append(mask) + + pixel_values = torch.stack(pixel_values) + pixel_masks = torch.stack(pixel_masks) + spatial_shapes = torch.tensor(spatial_shapes) + + batch_feature = BatchFeature( + data={ + "pixel_values": pixel_values, + "pixel_attention_mask": pixel_masks, + "spatial_shapes": spatial_shapes, + }, + tensor_type=return_tensors, + ) + return batch_feature + + +__all__ = ["Siglip2ImageProcessorFast"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/siglip2/modeling_siglip2.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/siglip2/modeling_siglip2.py new file mode 100644 index 0000000000000000000000000000000000000000..9c6e5569b29c7fd2f22019f8340f7b5149b2e3b9 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/siglip2/modeling_siglip2.py @@ -0,0 +1,1145 @@ +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# This file was automatically generated from src/transformers/models/siglip2/modular_siglip2.py. +# Do NOT edit this file manually as any edits will be overwritten by the generation of +# the file from the modular. If any change should be done, please apply the change to the +# modular_siglip2.py file directly. One of our CI enforces this. +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# Copyright 2025 The HuggingFace Inc. team. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +from collections.abc import Callable +from dataclasses import dataclass +from typing import Any + +import numpy as np +import torch +import torch.nn as nn +import torch.nn.functional as F + +from ... import initialization as init +from ...activations import ACT2FN +from ...masking_utils import create_bidirectional_mask +from ...modeling_layers import GradientCheckpointingLayer +from ...modeling_outputs import BaseModelOutput, BaseModelOutputWithPooling, ImageClassifierOutput +from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel +from ...processing_utils import Unpack +from ...utils import ModelOutput, TransformersKwargs, auto_docstring, can_return_tuple, torch_compilable_check +from ...utils.generic import merge_with_config_defaults +from ...utils.output_capturing import capture_outputs +from .configuration_siglip2 import Siglip2Config, Siglip2TextConfig, Siglip2VisionConfig + + +@dataclass +@auto_docstring( + custom_intro=""" + Base class for vision model's outputs that also contains image embeddings of the pooling of the last hidden states. + """ +) +class Siglip2VisionOutput(ModelOutput): + r""" + image_embeds (`torch.FloatTensor` of shape `(batch_size, output_dim)` *optional* returned when model is initialized with `with_projection=True`): + The image embeddings obtained by applying the projection layer to the pooler_output. + """ + + image_embeds: torch.FloatTensor | None = None + last_hidden_state: torch.FloatTensor | None = None + hidden_states: tuple[torch.FloatTensor, ...] | None = None + attentions: tuple[torch.FloatTensor, ...] | None = None + + +@dataclass +@auto_docstring( + custom_intro=""" + Base class for text model's outputs that also contains a pooling of the last hidden states. + """ +) +class Siglip2TextOutput(ModelOutput): + r""" + text_embeds (`torch.FloatTensor` of shape `(batch_size, output_dim)` *optional* returned when model is initialized with `with_projection=True`): + The text embeddings obtained by applying the projection layer to the pooler_output. + """ + + text_embeds: torch.FloatTensor | None = None + last_hidden_state: torch.FloatTensor | None = None + hidden_states: tuple[torch.FloatTensor, ...] | None = None + attentions: tuple[torch.FloatTensor, ...] | None = None + + +@dataclass +@auto_docstring +class Siglip2Output(ModelOutput): + r""" + loss (`torch.FloatTensor` of shape `(1,)`, *optional*, returned when `return_loss` is `True`): + Contrastive loss for image-text similarity. + logits_per_image (`torch.FloatTensor` of shape `(image_batch_size, text_batch_size)`): + The scaled dot product scores between `image_embeds` and `text_embeds`. This represents the image-text + similarity scores. + logits_per_text (`torch.FloatTensor` of shape `(text_batch_size, image_batch_size)`): + The scaled dot product scores between `text_embeds` and `image_embeds`. This represents the text-image + similarity scores. + text_embeds (`torch.FloatTensor` of shape `(batch_size, output_dim`): + The text embeddings obtained by applying the projection layer to the pooled output of [`Siglip2TextModel`]. + image_embeds (`torch.FloatTensor` of shape `(batch_size, output_dim`): + The image embeddings obtained by applying the projection layer to the pooled output of [`Siglip2VisionModel`]. + text_model_output (`BaseModelOutputWithPooling`): + The output of the [`Siglip2TextModel`]. + vision_model_output (`BaseModelOutputWithPooling`): + The output of the [`Siglip2VisionModel`]. + """ + + loss: torch.FloatTensor | None = None + logits_per_image: torch.FloatTensor | None = None + logits_per_text: torch.FloatTensor | None = None + text_embeds: torch.FloatTensor | None = None + image_embeds: torch.FloatTensor | None = None + text_model_output: BaseModelOutputWithPooling = None + vision_model_output: BaseModelOutputWithPooling = None + + def to_tuple(self) -> tuple[Any]: + return tuple( + self[k] if k not in ["text_model_output", "vision_model_output"] else getattr(self, k).to_tuple() + for k in self.keys() + ) + + +class Siglip2VisionEmbeddings(nn.Module): + def __init__(self, config: Siglip2VisionConfig): + super().__init__() + self.config = config + self.embed_dim = config.hidden_size + self.patch_size = config.patch_size + + self.patch_embedding = nn.Linear( + in_features=config.num_channels * self.patch_size * self.patch_size, + out_features=self.embed_dim, + ) + + self.num_patches = config.num_patches + self.position_embedding_size = int(self.num_patches**0.5) + self.position_embedding = nn.Embedding(self.num_patches, self.embed_dim) + + @staticmethod + def resize_positional_embeddings( + positional_embeddings: torch.Tensor, + spatial_shapes: torch.LongTensor, + max_length: int, + ) -> torch.Tensor: + """ + Resize positional embeddings to image-specific size and pad to a fixed size. + + Args: + positional_embeddings (`torch.Tensor`): + Position embeddings of shape (height, width, embed_dim) + spatial_shapes (`torch.LongTensor`): + Spatial shapes of shape (batch_size, 2) to resize the positional embeddings to + max_length (`int`): + Maximum length of the positional embeddings to pad resized positional embeddings to + + Returns: + `torch.Tensor`: Embeddings of shape (batch_size, max_length, embed_dim) + """ + batch_size = spatial_shapes.shape[0] + embed_dim = positional_embeddings.shape[-1] + source_dtype = positional_embeddings.dtype + + resulted_positional_embeddings = torch.empty( + (batch_size, max_length, embed_dim), + device=positional_embeddings.device, + dtype=source_dtype, + ) + + # (height, width, embed_dim) -> (1, embed_dim, height, width) for interpolation + positional_embeddings = positional_embeddings.permute(2, 0, 1).unsqueeze(0) + + # Upcast to float32 on CPU because antialias is not supported for bfloat16/float16 on CPU + if positional_embeddings.device.type == "cpu": + positional_embeddings = positional_embeddings.to(torch.float32) + + for i in range(batch_size): + # (1, dim, height, width) -> (1, dim, target_height, target_width) + height, width = spatial_shapes[i].tolist() # will be itemized in F.interpolate either way + torch_compilable_check((width > 0), "Width of resized positional embeddings must be positive.") + torch_compilable_check((height > 0), "Height of resized positional embeddings must be positive.") + torch_compilable_check((height * width) <= max_length, "Resized positional embeddings exceed max_length.") + resized_embeddings = F.interpolate( + positional_embeddings, + size=(height, width), + mode="bilinear", + align_corners=False, + antialias=True, + ) + + # (1, dim, target_height, target_width) -> (target_height * target_width, dim) + resized_embeddings = resized_embeddings.reshape(embed_dim, height * width).transpose(0, 1) + + # Cast to original dtype + resized_embeddings = resized_embeddings.to(source_dtype) + + resulted_positional_embeddings[i, : height * width] = resized_embeddings + resulted_positional_embeddings[i, height * width :] = resized_embeddings[0] + + return resulted_positional_embeddings + + def forward(self, pixel_values: torch.FloatTensor, spatial_shapes: torch.LongTensor) -> torch.Tensor: + """ + Args: + pixel_values (`torch.FloatTensor`): + Pixel values of shape (batch_size, max_num_patches, num_channels * patch_size * patch_size) + spatial_shapes (`list[tuple[int, int]]`): + Spatial shapes of shape (batch_size, 2) to resize the positional embeddings to + """ + + # Apply patch embeddings to already patchified pixel values + target_dtype = self.patch_embedding.weight.dtype + patch_embeds = self.patch_embedding(pixel_values.to(dtype=target_dtype)) + + # Get positional resized and padded positional embeddings + positional_embeddings = self.position_embedding.weight.reshape( + self.position_embedding_size, self.position_embedding_size, -1 + ) + resized_positional_embeddings = self.resize_positional_embeddings( + positional_embeddings, spatial_shapes, max_length=pixel_values.shape[1] + ) + + # Add positional embeddings to patch embeddings + embeddings = patch_embeds + resized_positional_embeddings + return embeddings + + +class Siglip2TextEmbeddings(nn.Module): + def __init__(self, config: Siglip2TextConfig): + super().__init__() + embed_dim = config.hidden_size + + self.token_embedding = nn.Embedding(config.vocab_size, embed_dim) + self.position_embedding = nn.Embedding(config.max_position_embeddings, embed_dim) + + # position_ids (1, len position emb) is contiguous in memory and exported when serialized + self.register_buffer( + "position_ids", torch.arange(config.max_position_embeddings).expand((1, -1)), persistent=False + ) + + def forward( + self, + input_ids: torch.LongTensor | None = None, + position_ids: torch.LongTensor | None = None, + inputs_embeds: torch.FloatTensor | None = None, + ) -> torch.Tensor: + seq_length = input_ids.shape[-1] if input_ids is not None else inputs_embeds.shape[-2] + max_position_embedding = self.position_embedding.weight.shape[0] + + if seq_length > max_position_embedding: + raise ValueError( + f"Sequence length must be less than max_position_embeddings (got `sequence length`: " + f"{seq_length} and max_position_embeddings: {max_position_embedding}" + ) + + if position_ids is None: + position_ids = self.position_ids[:, :seq_length] + + if inputs_embeds is None: + inputs_embeds = self.token_embedding(input_ids) + + position_embeddings = self.position_embedding(position_ids) + embeddings = inputs_embeds + position_embeddings + + return embeddings + + +def eager_attention_forward( + module: nn.Module, + query: torch.Tensor, + key: torch.Tensor, + value: torch.Tensor, + attention_mask: torch.Tensor | None, + scaling: float, + dropout: float = 0.0, + **kwargs, +): + attn_weights = torch.matmul(query, key.transpose(-1, -2)) * scaling + if attention_mask is not None: + attn_weights = attn_weights + attention_mask + + attn_weights = nn.functional.softmax(attn_weights, dim=-1, dtype=torch.float32).to(query.dtype) + attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training) + + attn_output = torch.matmul(attn_weights, value) + attn_output = attn_output.transpose(1, 2).contiguous() + + return attn_output, attn_weights + + +class Siglip2Attention(nn.Module): + """Multi-headed attention from 'Attention Is All You Need' paper""" + + def __init__(self, config): + super().__init__() + self.config = config + self.embed_dim = config.hidden_size + self.num_heads = config.num_attention_heads + self.head_dim = self.embed_dim // self.num_heads + if self.head_dim * self.num_heads != self.embed_dim: + raise ValueError( + f"embed_dim must be divisible by num_heads (got `embed_dim`: {self.embed_dim} and `num_heads`:" + f" {self.num_heads})." + ) + self.scale = self.head_dim**-0.5 + self.dropout = config.attention_dropout + self.is_causal = False + + self.k_proj = nn.Linear(self.embed_dim, self.embed_dim) + self.v_proj = nn.Linear(self.embed_dim, self.embed_dim) + self.q_proj = nn.Linear(self.embed_dim, self.embed_dim) + self.out_proj = nn.Linear(self.embed_dim, self.embed_dim) + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.Tensor | None = None, + **kwargs, + ) -> tuple[torch.Tensor, torch.Tensor | None]: + """Input shape: Batch x Time x Channel""" + + batch_size, seq_length, embed_dim = hidden_states.shape + + queries = self.q_proj(hidden_states) + keys = self.k_proj(hidden_states) + values = self.v_proj(hidden_states) + + queries = queries.view(batch_size, seq_length, self.num_heads, self.head_dim).transpose(1, 2) + keys = keys.view(batch_size, seq_length, self.num_heads, self.head_dim).transpose(1, 2) + values = values.view(batch_size, seq_length, self.num_heads, self.head_dim).transpose(1, 2) + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, eager_attention_forward + ) + + attn_output, attn_weights = attention_interface( + self, + queries, + keys, + values, + attention_mask, + is_causal=self.is_causal, + scaling=self.scale, + dropout=0.0 if not self.training else self.dropout, + ) + + attn_output = attn_output.reshape(batch_size, seq_length, embed_dim).contiguous() + attn_output = self.out_proj(attn_output) + + return attn_output, attn_weights + + +class Siglip2MLP(nn.Module): + def __init__(self, config): + super().__init__() + self.config = config + self.activation_fn = ACT2FN[config.hidden_act] + self.fc1 = nn.Linear(config.hidden_size, config.intermediate_size) + self.fc2 = nn.Linear(config.intermediate_size, config.hidden_size) + + def forward(self, hidden_states: torch.Tensor) -> torch.Tensor: + hidden_states = self.fc1(hidden_states) + hidden_states = self.activation_fn(hidden_states) + hidden_states = self.fc2(hidden_states) + return hidden_states + + +class Siglip2EncoderLayer(GradientCheckpointingLayer): + def __init__(self, config: Siglip2VisionConfig | Siglip2TextConfig): + super().__init__() + self.embed_dim = config.hidden_size + self.layer_norm1 = nn.LayerNorm(self.embed_dim, eps=config.layer_norm_eps) + self.self_attn = Siglip2Attention(config) + self.layer_norm2 = nn.LayerNorm(self.embed_dim, eps=config.layer_norm_eps) + self.mlp = Siglip2MLP(config) + + @auto_docstring + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.Tensor, + **kwargs: Unpack[TransformersKwargs], + ) -> torch.FloatTensor: + residual = hidden_states + + hidden_states = self.layer_norm1(hidden_states) + hidden_states, _ = self.self_attn( + hidden_states=hidden_states, + attention_mask=attention_mask, + **kwargs, + ) + hidden_states = residual + hidden_states + + residual = hidden_states + hidden_states = self.layer_norm2(hidden_states) + hidden_states = self.mlp(hidden_states) + hidden_states = residual + hidden_states + + return hidden_states + + +@auto_docstring +class Siglip2PreTrainedModel(PreTrainedModel): + config: Siglip2Config + base_model_prefix = "siglip2" + input_modalities = ("image", "text") + supports_gradient_checkpointing = True + + _no_split_modules = [ + "Siglip2TextEmbeddings", + "Siglip2VisionEmbeddings", + "Siglip2EncoderLayer", + "Siglip2MultiheadAttentionPoolingHead", + ] + _supports_flash_attn = False + _supports_sdpa = True + # nn.MultiHeadAttention mask doesn't allow for non 4d mask + _supports_flex_attn = False + _supports_attention_backend = True + + _can_record_outputs = { + "hidden_states": Siglip2EncoderLayer, + "attentions": Siglip2Attention, + } + + @torch.no_grad() + def _init_weights(self, module): + """Initialize the weights""" + if isinstance(module, Siglip2VisionEmbeddings): + width = ( + self.config.vision_config.hidden_size + if isinstance(self.config, Siglip2Config) + else self.config.hidden_size + ) + init.normal_(module.position_embedding.weight, std=1 / np.sqrt(width)) + if hasattr(module, "position_ids"): + init.copy_(module.position_ids, torch.arange(module.position_ids.shape[-1]).expand((1, -1))) + elif isinstance(module, nn.Embedding): + init.default_flax_embed_init_(module.weight) + elif isinstance(module, Siglip2Attention): + init.xavier_uniform_(module.q_proj.weight) + init.xavier_uniform_(module.k_proj.weight) + init.xavier_uniform_(module.v_proj.weight) + init.xavier_uniform_(module.out_proj.weight) + init.zeros_(module.q_proj.bias) + init.zeros_(module.k_proj.bias) + init.zeros_(module.v_proj.bias) + init.zeros_(module.out_proj.bias) + elif isinstance(module, Siglip2MLP): + init.xavier_uniform_(module.fc1.weight) + init.xavier_uniform_(module.fc2.weight) + init.normal_(module.fc1.bias, std=1e-6) + init.normal_(module.fc2.bias, std=1e-6) + elif isinstance(module, Siglip2MultiheadAttentionPoolingHead): + init.xavier_uniform_(module.probe) + init.xavier_uniform_(module.attention.in_proj_weight) + init.zeros_(module.attention.in_proj_bias) + elif isinstance(module, Siglip2Model): + init.zeros_(module.logit_scale) + init.zeros_(module.logit_bias) + elif isinstance(module, Siglip2ForImageClassification): + init.normal_( + module.classifier.weight, + std=self.config.vision_config.hidden_size**-0.5 * self.config.initializer_factor, + ) + elif isinstance(module, (nn.Linear, nn.Conv2d)): + init.lecun_normal_(module.weight) + if module.bias is not None: + init.zeros_(module.bias) + elif isinstance(module, nn.LayerNorm): + init.zeros_(module.bias) + init.ones_(module.weight) + elif isinstance(module, Siglip2TextEmbeddings): + init.copy_(module.position_ids, torch.arange(module.position_ids.shape[-1]).expand((1, -1))) + + +class Siglip2Encoder(nn.Module): + """ + Transformer encoder consisting of `config.num_hidden_layers` self attention layers. Each layer is a + [`Siglip2EncoderLayer`]. + + Args: + config: Siglip2Config + """ + + def __init__(self, config: Siglip2Config): + super().__init__() + self.config = config + self.layers = nn.ModuleList([Siglip2EncoderLayer(config) for _ in range(config.num_hidden_layers)]) + self.gradient_checkpointing = False + + # Ignore copy + @auto_docstring + def forward( + self, + inputs_embeds, + attention_mask: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> BaseModelOutput: + hidden_states = inputs_embeds + for encoder_layer in self.layers: + hidden_states = encoder_layer( + hidden_states, + attention_mask, + **kwargs, + ) + + return BaseModelOutput(last_hidden_state=hidden_states) + + +class Siglip2VisionTransformer(Siglip2PreTrainedModel): + _input_embed_layer = "patch_embedding" + + def __init__(self, config: Siglip2VisionConfig): + super().__init__(config) + self.config = config + embed_dim = config.hidden_size + + self.embeddings = Siglip2VisionEmbeddings(config) + self.encoder = Siglip2Encoder(config) + self.post_layernorm = nn.LayerNorm(embed_dim, eps=config.layer_norm_eps) + self.use_head = True if not hasattr(config, "vision_use_head") else config.vision_use_head + if self.use_head: + self.head = Siglip2MultiheadAttentionPoolingHead(config) + + self.post_init() + + @auto_docstring + def forward( + self, + pixel_values: torch.FloatTensor, + attention_mask: torch.Tensor, + spatial_shapes: torch.LongTensor, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + **kwargs, + ) -> BaseModelOutputWithPooling: + r""" + spatial_shapes (`torch.LongTensor` of shape `(batch_size, 2)`): + Tensor containing the spatial dimensions (height, width) of the input images. + """ + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + + hidden_states = self.embeddings(pixel_values, spatial_shapes) + + encoder_attention_mask = create_bidirectional_mask( + config=self.config, + inputs_embeds=hidden_states, + attention_mask=attention_mask, + ) + + encoder_outputs: BaseModelOutput = self.encoder( + inputs_embeds=hidden_states, + attention_mask=encoder_attention_mask, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + ) + + last_hidden_state = encoder_outputs.last_hidden_state + last_hidden_state = self.post_layernorm(last_hidden_state) + + pooler_output = self.head(last_hidden_state, attention_mask) if self.use_head else None + + return BaseModelOutputWithPooling( + last_hidden_state=last_hidden_state, + pooler_output=pooler_output, + hidden_states=encoder_outputs.hidden_states, + attentions=encoder_outputs.attentions, + ) + + +class Siglip2TextTransformer(Siglip2PreTrainedModel): + _input_embed_layer = "token_embedding" + + def __init__(self, config: Siglip2TextConfig): + super().__init__(config) + self.config = config + embed_dim = config.hidden_size + self.embeddings = Siglip2TextEmbeddings(config) + self.encoder = Siglip2Encoder(config) + self.final_layer_norm = nn.LayerNorm(embed_dim, eps=config.layer_norm_eps) + + self.head = nn.Linear(embed_dim, config.projection_size) + self.post_init() + + @can_return_tuple + @auto_docstring + def forward( + self, + input_ids: torch.Tensor | None = None, + attention_mask: torch.Tensor | None = None, + position_ids: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> BaseModelOutputWithPooling: + if input_ids is None: + raise ValueError("You have to specify input_ids") + + input_shape = input_ids.size() + input_ids = input_ids.view(-1, input_shape[-1]) + + hidden_states = self.embeddings(input_ids=input_ids, position_ids=position_ids) + + # note: Siglip2's text model does not use a causal mask, unlike the original CLIP model. + attention_mask = create_bidirectional_mask( + config=self.config, + inputs_embeds=hidden_states, + attention_mask=attention_mask, + ) + + encoder_outputs: BaseModelOutput = self.encoder( + inputs_embeds=hidden_states, + attention_mask=attention_mask, + **kwargs, + ) + + last_hidden_state = encoder_outputs.last_hidden_state + last_hidden_state = self.final_layer_norm(last_hidden_state) + + # The model uses the last token's hidden state, which may be padding. + pooled_output = last_hidden_state[:, -1, :] + pooled_output = self.head(pooled_output) + + return BaseModelOutputWithPooling( + last_hidden_state=last_hidden_state, + pooler_output=pooled_output, + ) + + +@auto_docstring( + custom_intro=""" + The text model from Siglip2 without any head or projection on top. + """ +) +class Siglip2TextModel(Siglip2PreTrainedModel): + config: Siglip2TextConfig + input_modalities = ("text",) + + def __init__(self, config: Siglip2TextConfig): + super().__init__(config) + self.text_model = Siglip2TextTransformer(config) + # Initialize weights and apply final processing + self.post_init() + + def get_input_embeddings(self) -> nn.Module: + return self.text_model.embeddings.token_embedding + + def set_input_embeddings(self, value): + self.text_model.embeddings.token_embedding = value + + @merge_with_config_defaults + @capture_outputs(tie_last_hidden_states=False) + @auto_docstring + def forward( + self, + input_ids: torch.Tensor | None = None, + attention_mask: torch.Tensor | None = None, + position_ids: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> BaseModelOutputWithPooling: + r""" + Examples: + + ```python + >>> from transformers import AutoTokenizer, Siglip2TextModel + + >>> model = Siglip2TextModel.from_pretrained("google/siglip2-base-patch16-224") + >>> tokenizer = AutoTokenizer.from_pretrained("google/siglip2-base-patch16-224") + + >>> # important: make sure to set padding="max_length" as that's how the model was trained + >>> inputs = tokenizer(["a photo of a cat", "a photo of a dog"], padding="max_length", return_tensors="pt") + + >>> outputs = model(**inputs) + >>> last_hidden_state = outputs.last_hidden_state + >>> pooled_output = outputs.pooler_output # pooled (EOS token) states + ```""" + + return self.text_model( + input_ids=input_ids, + attention_mask=attention_mask, + position_ids=position_ids, + **kwargs, + ) + + +class Siglip2MultiheadAttentionPoolingHead(nn.Module): + """Multihead Attention Pooling.""" + + def __init__(self, config: Siglip2VisionConfig): + super().__init__() + + self.probe = nn.Parameter(torch.randn(1, 1, config.hidden_size)) + self.attention = torch.nn.MultiheadAttention(config.hidden_size, config.num_attention_heads, batch_first=True) + self.layernorm = nn.LayerNorm(config.hidden_size, eps=config.layer_norm_eps) + self.mlp = Siglip2MLP(config) + + self.config = config + self.num_heads = config.num_attention_heads + + def forward(self, hidden_state: torch.Tensor, attention_mask: torch.Tensor | None = None) -> torch.Tensor: + batch_size = hidden_state.shape[0] + probe = self.probe.repeat(batch_size, 1, 1) + + if attention_mask is not None: + target_len, source_len = probe.shape[1], hidden_state.shape[1] + attention_mask = create_bidirectional_mask( + config=self.config, + inputs_embeds=probe, + attention_mask=attention_mask, + encoder_hidden_states=hidden_state, + ) + if attention_mask is not None: + attention_mask = attention_mask.repeat(1, self.num_heads, target_len, 1) + attention_mask = attention_mask.reshape(-1, target_len, source_len) + + # `nn.MultiheadAttention` cannot handle boolean masks (which SDPA can) + if attention_mask.dtype == torch.bool: + attention_mask = torch.where( + attention_mask, + torch.tensor(0.0, device=attention_mask.device, dtype=probe.dtype), + torch.finfo(probe.dtype).min, + ) + + hidden_state = self.attention(probe, hidden_state, hidden_state, attn_mask=attention_mask)[0] + + residual = hidden_state + hidden_state = self.layernorm(hidden_state) + hidden_state = residual + self.mlp(hidden_state) + + return hidden_state[:, 0] + + +@auto_docstring( + custom_intro=""" + The vision model from Siglip2 without any head or projection on top. + """ +) +class Siglip2VisionModel(Siglip2PreTrainedModel): + config: Siglip2VisionConfig + main_input_name = "pixel_values" + input_modalities = ("image",) + + def __init__(self, config: Siglip2VisionConfig): + super().__init__(config) + + self.vision_model = Siglip2VisionTransformer(config) + + # Initialize weights and apply final processing + self.post_init() + + def get_input_embeddings(self) -> nn.Module: + return self.vision_model.embeddings.patch_embedding + + @merge_with_config_defaults + @capture_outputs(tie_last_hidden_states=False) + @auto_docstring + def forward( + self, + pixel_values: torch.FloatTensor, + pixel_attention_mask: torch.Tensor, + spatial_shapes: torch.LongTensor, + **kwargs: Unpack[TransformersKwargs], + ) -> BaseModelOutputWithPooling: + r""" + pixel_attention_mask (`torch.Tensor` of shape `(batch_size, image_size, image_size)`, *optional*): + Mask to avoid performing attention on padding pixel indices. + spatial_shapes (`torch.LongTensor` of shape `(batch_size, 2)`): + Tensor containing the spatial dimensions (height, width) of the input images. + + Examples: + + ```python + >>> from PIL import Image + >>> import httpx + >>> from io import BytesIO + >>> from transformers import AutoProcessor, Siglip2VisionModel + + >>> model = Siglip2VisionModel.from_pretrained("google/siglip2-base-patch16-224") + >>> processor = AutoProcessor.from_pretrained("google/siglip2-base-patch16-224") + + >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg" + >>> with httpx.stream("GET", url) as response: + ... image = Image.open(BytesIO(response.read())) + + >>> inputs = processor(images=image, return_tensors="pt") + + >>> outputs = model(**inputs) + >>> last_hidden_state = outputs.last_hidden_state + >>> pooled_output = outputs.pooler_output # pooled features + ```""" + return self.vision_model( + pixel_values=pixel_values, + attention_mask=pixel_attention_mask, + spatial_shapes=spatial_shapes, + **kwargs, + ) + + +@auto_docstring +class Siglip2Model(Siglip2PreTrainedModel): + config: Siglip2Config + + def __init__(self, config: Siglip2Config): + super().__init__(config) + + if not isinstance(config.text_config, Siglip2TextConfig): + raise TypeError( + "config.text_config is expected to be of type Siglip2TextConfig but is of type" + f" {type(config.text_config)}." + ) + + if not isinstance(config.vision_config, Siglip2VisionConfig): + raise TypeError( + "config.vision_config is expected to be of type Siglip2VisionConfig but is of type" + f" {type(config.vision_config)}." + ) + + text_config = config.text_config + vision_config = config.vision_config + + # First, initialize the text and vision models with proper attention implementation + text_model = Siglip2TextModel._from_config(text_config) + vision_model = Siglip2VisionModel._from_config(vision_config) + + # Second, get the text and vision submodules (for backward compatibility) + self.text_model = text_model.text_model + self.vision_model = vision_model.vision_model + + self.logit_scale = nn.Parameter(torch.randn(1)) + self.logit_bias = nn.Parameter(torch.randn(1)) + + # Initialize weights and apply final processing + self.post_init() + + def get_input_embeddings(self) -> nn.Module: + return self.text_model.embeddings.token_embedding + + def set_input_embeddings(self, value: nn.Module): + self.text_model.embeddings.token_embedding = value + + @can_return_tuple + @auto_docstring + def get_text_features( + self, + input_ids: torch.Tensor, + attention_mask: torch.Tensor | None = None, + position_ids: torch.Tensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple | BaseModelOutputWithPooling: + r""" + Examples: + + ```python + >>> from transformers import AutoTokenizer, AutoModel + >>> import torch + + >>> model = AutoModel.from_pretrained("google/siglip2-base-patch16-224") + >>> tokenizer = AutoTokenizer.from_pretrained("google/siglip2-base-patch16-224") + + >>> # important: make sure to set padding="max_length" as that's how the model was trained + >>> inputs = tokenizer(["a photo of a cat", "a photo of a dog"], padding="max_length", return_tensors="pt") + >>> with torch.no_grad(): + ... text_features = model.get_text_features(**inputs) + ```""" + return self.text_model( + input_ids=input_ids, + attention_mask=attention_mask, + position_ids=position_ids, + **kwargs, + ) + + @can_return_tuple + @auto_docstring + def get_image_features( + self, + pixel_values: torch.FloatTensor | None = None, + pixel_attention_mask: torch.Tensor | None = None, + spatial_shapes: torch.LongTensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple | BaseModelOutputWithPooling: + r""" + pixel_attention_mask (`torch.Tensor` of shape `(batch_size, image_size, image_size)`, *optional*): + Mask to avoid performing attention on padding pixel indices. + spatial_shapes (`torch.LongTensor` of shape `(batch_size, 2)`): + Tensor containing the spatial dimensions (height, width) of the input images. + + Examples: + + ```python + >>> import torch + >>> from transformers import AutoProcessor, AutoModel + >>> from transformers.image_utils import load_image + + >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg" + >>> image = load_image(url) + + >>> model = AutoModel.from_pretrained("google/siglip2-base-patch16-224") + >>> processor = AutoProcessor.from_pretrained("google/siglip2-base-patch16-224") + + >>> inputs = processor(images=image, return_tensors="pt") + + >>> with torch.no_grad(): + ... image_features = model.get_image_features(**inputs) + ``` + """ + return self.vision_model( + pixel_values=pixel_values, + attention_mask=pixel_attention_mask, + spatial_shapes=spatial_shapes, + **kwargs, + ) + + # NOTE: Siglip2Model uses Pretrained backbones, so we don't need to add `capture_outputs` here + @can_return_tuple + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + pixel_values: torch.FloatTensor | None = None, + pixel_attention_mask: torch.Tensor | None = None, + spatial_shapes: torch.LongTensor | None = None, + attention_mask: torch.Tensor | None = None, + position_ids: torch.LongTensor | None = None, + return_loss: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + **kwargs, + ) -> Siglip2Output: + r""" + pixel_attention_mask (`torch.Tensor` of shape `(batch_size, image_size, image_size)`, *optional*): + Mask to avoid performing attention on padding pixel indices. + spatial_shapes (`torch.LongTensor` of shape `(batch_size, 2)`): + Tensor containing the spatial dimensions (height, width) of the input images. + return_loss (`bool`, *optional*): + Whether or not to return the contrastive loss. + + Examples: + + ```python + >>> from PIL import Image + >>> import httpx + >>> from io import BytesIO + >>> from transformers import AutoProcessor, AutoModel + >>> import torch + + >>> model = AutoModel.from_pretrained("google/siglip2-base-patch16-224") + >>> processor = AutoProcessor.from_pretrained("google/siglip2-base-patch16-224") + + >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg" + >>> with httpx.stream("GET", url) as response: + ... image = Image.open(BytesIO(response.read())) + + >>> texts = ["a photo of 2 cats", "a photo of 2 dogs"] + >>> # important: we pass `padding=max_length` since the model was trained with this + >>> inputs = processor(text=texts, images=image, padding="max_length", return_tensors="pt") + + >>> with torch.no_grad(): + ... outputs = model(**inputs) + + >>> logits_per_image = outputs.logits_per_image + >>> probs = torch.sigmoid(logits_per_image) # these are the probabilities + >>> print(f"{probs[0][0]:.1%} that image 0 is '{texts[0]}'") + 31.9% that image 0 is 'a photo of 2 cats' + ``` + """ + # Use Siglip2 model's config for some fields (if specified) instead of those of vision & text components. + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + + vision_outputs: BaseModelOutputWithPooling = self.vision_model( + pixel_values=pixel_values, + attention_mask=pixel_attention_mask, + spatial_shapes=spatial_shapes, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + ) + + text_outputs: BaseModelOutputWithPooling = self.text_model( + input_ids=input_ids, + attention_mask=attention_mask, + position_ids=position_ids, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + ) + + image_embeds = vision_outputs.pooler_output + text_embeds = text_outputs.pooler_output + + # normalized features + image_embeds = image_embeds / image_embeds.norm(p=2, dim=-1, keepdim=True) + text_embeds = text_embeds / text_embeds.norm(p=2, dim=-1, keepdim=True) + + # cosine similarity as logits + logits_per_text = torch.matmul(text_embeds, image_embeds.t().to(text_embeds.device)) + + logit_scale, logit_bias = self.logit_scale.to(text_embeds.device), self.logit_bias.to(text_embeds.device) + logits_per_text = logits_per_text * logit_scale.exp() + logit_bias + + logits_per_image = logits_per_text.t() + + loss = None + if return_loss: + # Adapted from https://github.com/google-research/big_vision/blob/01edb81a4716f93a48be43b3a4af14e29cdb3a7f/big_vision/trainers/proj/image_text/siglip2.py#L287 + eye = torch.eye(logits_per_text.size(0), device=logits_per_text.device) + m1_diag1 = -torch.ones_like(logits_per_text) + 2 * eye + loglik = torch.nn.functional.logsigmoid(m1_diag1 * logits_per_text) + nll = -torch.sum(loglik, dim=-1) + loss = nll.mean() + + return Siglip2Output( + loss=loss, + logits_per_image=logits_per_image, + logits_per_text=logits_per_text, + text_embeds=text_embeds, + image_embeds=image_embeds, + text_model_output=text_outputs, + vision_model_output=vision_outputs, + ) + + +@auto_docstring( + custom_intro=""" + Siglip2 vision encoder with an image classification head on top (a linear layer on top of the pooled final hidden states of + the patch tokens) e.g. for ImageNet. + """ +) +class Siglip2ForImageClassification(Siglip2PreTrainedModel): + main_input_name = "pixel_values" + input_modalities = ("image",) + + def __init__(self, config: Siglip2Config) -> None: + super().__init__(config) + + self.num_labels = config.num_labels + + # Create the vision model with proper attention + # and take only vision_model submodule (for backward compatibility) + vision_model = Siglip2VisionModel._from_config(config.vision_config) + self.vision_model = vision_model.vision_model + + # Classifier head + self.classifier = ( + nn.Linear(config.vision_config.hidden_size, config.num_labels) if config.num_labels > 0 else nn.Identity() + ) + + # Initialize weights and apply final processing + self.post_init() + + def get_input_embeddings(self) -> nn.Module: + return self.vision_model.embeddings.patch_embedding + + def set_input_embeddings(self, value: nn.Module): + self.vision_model.embeddings.patch_embedding = value + + @merge_with_config_defaults + @capture_outputs + @auto_docstring + def forward( + self, + pixel_values: torch.Tensor | None = None, + pixel_attention_mask: torch.Tensor | None = None, + spatial_shapes: torch.LongTensor | None = None, + labels: torch.Tensor | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + **kwargs, + ) -> ImageClassifierOutput: + r""" + pixel_attention_mask (`torch.Tensor` of shape `(batch_size, image_size, image_size)`, *optional*): + Mask to avoid performing attention on padding pixel indices. + spatial_shapes (`torch.LongTensor` of shape `(batch_size, 2)`): + Tensor containing the spatial dimensions (height, width) of the input images. + labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*): + Labels for computing the image classification/regression loss. Indices should be in `[0, ..., + config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If + `config.num_labels > 1` a classification loss is computed (Cross-Entropy). + + Examples: + + ```python + >>> from transformers import AutoImageProcessor, Siglip2ForImageClassification + >>> import torch + >>> from PIL import Image + >>> import httpx + >>> from io import BytesIO + + >>> torch.manual_seed(3) # doctest: +IGNORE_RESULT + >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg" + >>> with httpx.stream("GET", url) as response: + ... image = Image.open(BytesIO(response.read())) + + >>> # note: we are loading a `Siglip2Model` from the hub here, + >>> # so the head will be randomly initialized, hence the predictions will be random if seed is not set above. + >>> image_processor = AutoImageProcessor.from_pretrained("google/siglip2-base-patch16-224") + >>> model = Siglip2ForImageClassification.from_pretrained("google/siglip2-base-patch16-224") + + >>> inputs = image_processor(images=image, return_tensors="pt") + >>> outputs = model(**inputs) + >>> logits = outputs.logits + >>> # model predicts one of the two classes + >>> predicted_class_idx = logits.argmax(-1).item() + >>> print("Predicted class:", model.config.id2label[predicted_class_idx]) + Predicted class: LABEL_1 + ``` + """ + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + + outputs: BaseModelOutputWithPooling = self.vision_model( + pixel_values, + attention_mask=pixel_attention_mask, + spatial_shapes=spatial_shapes, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + ) + + sequence_output = outputs.last_hidden_state + + # average pool the patch tokens + if pixel_attention_mask is not None: + pool_mask = pixel_attention_mask[..., None].to(sequence_output.device) + sequence_output = torch.sum(sequence_output * pool_mask, dim=1) / torch.sum(pool_mask, dim=1) + else: + sequence_output = torch.mean(sequence_output, dim=1) + + # apply classifier + logits = self.classifier(sequence_output) + + loss = None + if labels is not None: + loss = self.loss_function(labels, logits, self.config) + + return ImageClassifierOutput( + loss=loss, + logits=logits, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + ) + + +__all__ = [ + "Siglip2Model", + "Siglip2PreTrainedModel", + "Siglip2TextModel", + "Siglip2VisionModel", + "Siglip2ForImageClassification", +] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/siglip2/modular_siglip2.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/siglip2/modular_siglip2.py new file mode 100644 index 0000000000000000000000000000000000000000..07c25658f76a18e18f77b167d66d19f6b8b944c4 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/siglip2/modular_siglip2.py @@ -0,0 +1,676 @@ +# Copyright 2025 The HuggingFace Inc. team. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import torch +import torch.nn as nn +import torch.nn.functional as F +from tokenizers import normalizers + +from transformers.models.gemma.tokenization_gemma import GemmaTokenizer +from transformers.models.siglip.configuration_siglip import SiglipConfig, SiglipTextConfig, SiglipVisionConfig +from transformers.models.siglip.modeling_siglip import ( + BaseModelOutput, + BaseModelOutputWithPooling, + ImageClassifierOutput, + SiglipForImageClassification, + SiglipModel, + SiglipMultiheadAttentionPoolingHead, + SiglipOutput, + SiglipPreTrainedModel, + SiglipTextModel, + SiglipTextModelOutput, + SiglipVisionModel, + SiglipVisionModelOutput, + SiglipVisionTransformer, +) + +from ...masking_utils import create_bidirectional_mask +from ...processing_utils import Unpack +from ...utils import ( + TransformersKwargs, + auto_docstring, + can_return_tuple, + torch_compilable_check, +) +from ...utils.generic import merge_with_config_defaults +from ...utils.output_capturing import capture_outputs + + +class Siglip2Tokenizer(GemmaTokenizer): + """ + Gemma tokenizer + SigLIP2 training default: lowercase normalization. + """ + + def __init__( + self, + vocab: str | dict[str, int] | None = None, + merges: str | list[str] | None = None, + unk_token: str = "", + bos_token: str = "", + eos_token: str = "", + pad_token: str = "", + mask_token: str = "", + **kwargs, + ): + super().__init__( + vocab=vocab, + merges=merges, + unk_token=unk_token, + bos_token=bos_token, + eos_token=eos_token, + pad_token=pad_token, + mask_token=mask_token, + **kwargs, + ) + + # Persist for save/load + push_to_hub dynamic tokenizer test + if hasattr(self, "init_kwargs") and isinstance(self.init_kwargs, dict): + self.init_kwargs.setdefault("tokenizer_class", self.__class__.__name__) + + backend = getattr(self, "_tokenizer", None) + if backend is not None and backend.normalizer is not None: + backend.normalizer = normalizers.Sequence([normalizers.Lowercase(), backend.normalizer]) + + +class Siglip2TextConfig(SiglipTextConfig): + pass + + +class Siglip2VisionConfig(SiglipVisionConfig): + r""" + This is the configuration class to store the configuration of a [`Siglip2VisionModel`]. It is used to instantiate a + Siglip2 vision encoder according to the specified arguments, defining the model architecture. Instantiating a + configuration with the defaults will yield a similar configuration to that of the vision encoder of the Siglip2 + [google/siglip2-base-patch16-naflex](https://huggingface.co/google/siglip2-base-patch16-naflex) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + hidden_size (`int`, *optional*, defaults to 768): + Dimensionality of the encoder layers and the pooler layer. + intermediate_size (`int`, *optional*, defaults to 3072): + Dimensionality of the "intermediate" (i.e., feed-forward) layer in the Transformer encoder. + num_hidden_layers (`int`, *optional*, defaults to 12): + Number of hidden layers in the Transformer encoder. + num_attention_heads (`int`, *optional*, defaults to 12): + Number of attention heads for each attention layer in the Transformer encoder. + num_channels (`int`, *optional*, defaults to 3): + Number of channels in the input images. + num_patches (`int`, *optional*, defaults to 256): + The number of patches in the image with the size of (`patch_size`, `patch_size`). + The image is resized to fill maximum of this number of patches, and to preserve + the aspect ratio. In case the resulted number of patches is lower, the image is + padded in "patch" dimension. + patch_size (`int`, *optional*, defaults to 16): + The size (resolution) of each patch. + hidden_act (`str` or `function`, *optional*, defaults to `"gelu_pytorch_tanh"`): + The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`, + `"relu"`, `"selu"` and `"gelu_new"` `"quick_gelu"` are supported. + layer_norm_eps (`float`, *optional*, defaults to 1e-06): + The epsilon used by the layer normalization layers. + attention_dropout (`float`, *optional*, defaults to 0.0): + The dropout ratio for the attention probabilities. + + Example: + + ```python + >>> from transformers import Siglip2VisionConfig, Siglip2VisionModel + + >>> # Initializing a Siglip2VisionConfig with google/siglip2-base-patch16-naflex style configuration + >>> configuration = Siglip2VisionConfig() + + >>> # Initializing a Siglip2VisionModel (with random weights) from the google/siglip2-base-patch16-naflex style configuration + >>> model = Siglip2VisionModel(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + def __init__( + self, + hidden_size=768, + intermediate_size=3072, + num_hidden_layers=12, + num_attention_heads=12, + num_channels=3, + num_patches=256, + patch_size=16, + hidden_act="gelu_pytorch_tanh", + layer_norm_eps=1e-6, + attention_dropout=0.0, + **kwargs, + ): + super().__init__(**kwargs) + self.num_patches = num_patches + del self.image_size + + +class Siglip2Config(SiglipConfig): + pass + + +class Siglip2VisionOutput(SiglipVisionModelOutput): + pass + + +class Siglip2TextOutput(SiglipTextModelOutput): + pass + + +class Siglip2Output(SiglipOutput): + pass + + +class Siglip2VisionEmbeddings(nn.Module): + def __init__(self, config: Siglip2VisionConfig): + super().__init__() + self.config = config + self.embed_dim = config.hidden_size + self.patch_size = config.patch_size + + self.patch_embedding = nn.Linear( + in_features=config.num_channels * self.patch_size * self.patch_size, + out_features=self.embed_dim, + ) + + self.num_patches = config.num_patches + self.position_embedding_size = int(self.num_patches**0.5) + self.position_embedding = nn.Embedding(self.num_patches, self.embed_dim) + + @staticmethod + def resize_positional_embeddings( + positional_embeddings: torch.Tensor, + spatial_shapes: torch.LongTensor, + max_length: int, + ) -> torch.Tensor: + """ + Resize positional embeddings to image-specific size and pad to a fixed size. + + Args: + positional_embeddings (`torch.Tensor`): + Position embeddings of shape (height, width, embed_dim) + spatial_shapes (`torch.LongTensor`): + Spatial shapes of shape (batch_size, 2) to resize the positional embeddings to + max_length (`int`): + Maximum length of the positional embeddings to pad resized positional embeddings to + + Returns: + `torch.Tensor`: Embeddings of shape (batch_size, max_length, embed_dim) + """ + batch_size = spatial_shapes.shape[0] + embed_dim = positional_embeddings.shape[-1] + source_dtype = positional_embeddings.dtype + + resulted_positional_embeddings = torch.empty( + (batch_size, max_length, embed_dim), + device=positional_embeddings.device, + dtype=source_dtype, + ) + + # (height, width, embed_dim) -> (1, embed_dim, height, width) for interpolation + positional_embeddings = positional_embeddings.permute(2, 0, 1).unsqueeze(0) + + # Upcast to float32 on CPU because antialias is not supported for bfloat16/float16 on CPU + if positional_embeddings.device.type == "cpu": + positional_embeddings = positional_embeddings.to(torch.float32) + + for i in range(batch_size): + # (1, dim, height, width) -> (1, dim, target_height, target_width) + height, width = spatial_shapes[i].tolist() # will be itemized in F.interpolate either way + torch_compilable_check((width > 0), "Width of resized positional embeddings must be positive.") + torch_compilable_check((height > 0), "Height of resized positional embeddings must be positive.") + torch_compilable_check((height * width) <= max_length, "Resized positional embeddings exceed max_length.") + resized_embeddings = F.interpolate( + positional_embeddings, + size=(height, width), + mode="bilinear", + align_corners=False, + antialias=True, + ) + + # (1, dim, target_height, target_width) -> (target_height * target_width, dim) + resized_embeddings = resized_embeddings.reshape(embed_dim, height * width).transpose(0, 1) + + # Cast to original dtype + resized_embeddings = resized_embeddings.to(source_dtype) + + resulted_positional_embeddings[i, : height * width] = resized_embeddings + resulted_positional_embeddings[i, height * width :] = resized_embeddings[0] + + return resulted_positional_embeddings + + def forward(self, pixel_values: torch.FloatTensor, spatial_shapes: torch.LongTensor) -> torch.Tensor: + """ + Args: + pixel_values (`torch.FloatTensor`): + Pixel values of shape (batch_size, max_num_patches, num_channels * patch_size * patch_size) + spatial_shapes (`list[tuple[int, int]]`): + Spatial shapes of shape (batch_size, 2) to resize the positional embeddings to + """ + + # Apply patch embeddings to already patchified pixel values + target_dtype = self.patch_embedding.weight.dtype + patch_embeds = self.patch_embedding(pixel_values.to(dtype=target_dtype)) + + # Get positional resized and padded positional embeddings + positional_embeddings = self.position_embedding.weight.reshape( + self.position_embedding_size, self.position_embedding_size, -1 + ) + resized_positional_embeddings = self.resize_positional_embeddings( + positional_embeddings, spatial_shapes, max_length=pixel_values.shape[1] + ) + + # Add positional embeddings to patch embeddings + embeddings = patch_embeds + resized_positional_embeddings + return embeddings + + +class Siglip2PreTrainedModel(SiglipPreTrainedModel): + # nn.MultiHeadAttention mask doesn't allow for non 4d mask + _supports_flex_attn = False + _supports_flash_attn = False + + +class Siglip2VisionTransformer(SiglipVisionTransformer): + def __init__(self, config: Siglip2VisionConfig): + super().__init__(config) + + # Update: add `spatial_shapes` and `attention_mask` + def forward( + self, + pixel_values: torch.FloatTensor, + attention_mask: torch.Tensor, + spatial_shapes: torch.LongTensor, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + **kwargs, + ) -> BaseModelOutputWithPooling: + r""" + spatial_shapes (`torch.LongTensor` of shape `(batch_size, 2)`): + Tensor containing the spatial dimensions (height, width) of the input images. + """ + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + + hidden_states = self.embeddings(pixel_values, spatial_shapes) + + encoder_attention_mask = create_bidirectional_mask( + config=self.config, + inputs_embeds=hidden_states, + attention_mask=attention_mask, + ) + + encoder_outputs: BaseModelOutput = self.encoder( + inputs_embeds=hidden_states, + attention_mask=encoder_attention_mask, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + ) + + last_hidden_state = encoder_outputs.last_hidden_state + last_hidden_state = self.post_layernorm(last_hidden_state) + + pooler_output = self.head(last_hidden_state, attention_mask) if self.use_head else None + + return BaseModelOutputWithPooling( + last_hidden_state=last_hidden_state, + pooler_output=pooler_output, + hidden_states=encoder_outputs.hidden_states, + attentions=encoder_outputs.attentions, + ) + + +class Siglip2TextModel(SiglipTextModel): + pass + + +class Siglip2MultiheadAttentionPoolingHead(SiglipMultiheadAttentionPoolingHead): + def __init__(self, config: Siglip2VisionConfig): + super().__init__(config) + + self.config = config + self.num_heads = config.num_attention_heads + + def forward(self, hidden_state: torch.Tensor, attention_mask: torch.Tensor | None = None) -> torch.Tensor: + batch_size = hidden_state.shape[0] + probe = self.probe.repeat(batch_size, 1, 1) + + if attention_mask is not None: + target_len, source_len = probe.shape[1], hidden_state.shape[1] + attention_mask = create_bidirectional_mask( + config=self.config, + inputs_embeds=probe, + attention_mask=attention_mask, + encoder_hidden_states=hidden_state, + ) + if attention_mask is not None: + attention_mask = attention_mask.repeat(1, self.num_heads, target_len, 1) + attention_mask = attention_mask.reshape(-1, target_len, source_len) + + # `nn.MultiheadAttention` cannot handle boolean masks (which SDPA can) + if attention_mask.dtype == torch.bool: + attention_mask = torch.where( + attention_mask, + torch.tensor(0.0, device=attention_mask.device, dtype=probe.dtype), + torch.finfo(probe.dtype).min, + ) + + hidden_state = self.attention(probe, hidden_state, hidden_state, attn_mask=attention_mask)[0] + + residual = hidden_state + hidden_state = self.layernorm(hidden_state) + hidden_state = residual + self.mlp(hidden_state) + + return hidden_state[:, 0] + + +class Siglip2VisionModel(SiglipVisionModel): + # Update: add `spatial_shapes` and `pixel_attention_mask` + @merge_with_config_defaults + @capture_outputs(tie_last_hidden_states=False) + @auto_docstring + def forward( + self, + pixel_values: torch.FloatTensor, + pixel_attention_mask: torch.Tensor, + spatial_shapes: torch.LongTensor, + **kwargs: Unpack[TransformersKwargs], + ) -> BaseModelOutputWithPooling: + r""" + pixel_attention_mask (`torch.Tensor` of shape `(batch_size, image_size, image_size)`, *optional*): + Mask to avoid performing attention on padding pixel indices. + spatial_shapes (`torch.LongTensor` of shape `(batch_size, 2)`): + Tensor containing the spatial dimensions (height, width) of the input images. + + Examples: + + ```python + >>> from PIL import Image + >>> import httpx + >>> from io import BytesIO + >>> from transformers import AutoProcessor, Siglip2VisionModel + + >>> model = Siglip2VisionModel.from_pretrained("google/siglip2-base-patch16-224") + >>> processor = AutoProcessor.from_pretrained("google/siglip2-base-patch16-224") + + >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg" + >>> with httpx.stream("GET", url) as response: + ... image = Image.open(BytesIO(response.read())) + + >>> inputs = processor(images=image, return_tensors="pt") + + >>> outputs = model(**inputs) + >>> last_hidden_state = outputs.last_hidden_state + >>> pooled_output = outputs.pooler_output # pooled features + ```""" + return self.vision_model( + pixel_values=pixel_values, + attention_mask=pixel_attention_mask, + spatial_shapes=spatial_shapes, + **kwargs, + ) + + +class Siglip2Model(SiglipModel): + # Update: add `spatial_shapes` and `pixel_attention_mask` + @can_return_tuple + @auto_docstring + def get_image_features( + self, + pixel_values: torch.FloatTensor | None = None, + pixel_attention_mask: torch.Tensor | None = None, + spatial_shapes: torch.LongTensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple | BaseModelOutputWithPooling: + r""" + pixel_attention_mask (`torch.Tensor` of shape `(batch_size, image_size, image_size)`, *optional*): + Mask to avoid performing attention on padding pixel indices. + spatial_shapes (`torch.LongTensor` of shape `(batch_size, 2)`): + Tensor containing the spatial dimensions (height, width) of the input images. + + Examples: + + ```python + >>> import torch + >>> from transformers import AutoProcessor, AutoModel + >>> from transformers.image_utils import load_image + + >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg" + >>> image = load_image(url) + + >>> model = AutoModel.from_pretrained("google/siglip2-base-patch16-224") + >>> processor = AutoProcessor.from_pretrained("google/siglip2-base-patch16-224") + + >>> inputs = processor(images=image, return_tensors="pt") + + >>> with torch.no_grad(): + ... image_features = model.get_image_features(**inputs) + ``` + """ + return self.vision_model( + pixel_values=pixel_values, + attention_mask=pixel_attention_mask, + spatial_shapes=spatial_shapes, + **kwargs, + ) + + # Update: add `spatial_shapes` and `pixel_attention_mask` + def forward( + self, + input_ids: torch.LongTensor | None = None, + pixel_values: torch.FloatTensor | None = None, + pixel_attention_mask: torch.Tensor | None = None, + spatial_shapes: torch.LongTensor | None = None, + attention_mask: torch.Tensor | None = None, + position_ids: torch.LongTensor | None = None, + return_loss: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + **kwargs, + ) -> Siglip2Output: + r""" + pixel_attention_mask (`torch.Tensor` of shape `(batch_size, image_size, image_size)`, *optional*): + Mask to avoid performing attention on padding pixel indices. + spatial_shapes (`torch.LongTensor` of shape `(batch_size, 2)`): + Tensor containing the spatial dimensions (height, width) of the input images. + return_loss (`bool`, *optional*): + Whether or not to return the contrastive loss. + + Examples: + + ```python + >>> from PIL import Image + >>> import httpx + >>> from io import BytesIO + >>> from transformers import AutoProcessor, AutoModel + >>> import torch + + >>> model = AutoModel.from_pretrained("google/siglip2-base-patch16-224") + >>> processor = AutoProcessor.from_pretrained("google/siglip2-base-patch16-224") + + >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg" + >>> with httpx.stream("GET", url) as response: + ... image = Image.open(BytesIO(response.read())) + + >>> texts = ["a photo of 2 cats", "a photo of 2 dogs"] + >>> # important: we pass `padding=max_length` since the model was trained with this + >>> inputs = processor(text=texts, images=image, padding="max_length", return_tensors="pt") + + >>> with torch.no_grad(): + ... outputs = model(**inputs) + + >>> logits_per_image = outputs.logits_per_image + >>> probs = torch.sigmoid(logits_per_image) # these are the probabilities + >>> print(f"{probs[0][0]:.1%} that image 0 is '{texts[0]}'") + 31.9% that image 0 is 'a photo of 2 cats' + ``` + """ + # Use Siglip2 model's config for some fields (if specified) instead of those of vision & text components. + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + + vision_outputs: BaseModelOutputWithPooling = self.vision_model( + pixel_values=pixel_values, + attention_mask=pixel_attention_mask, + spatial_shapes=spatial_shapes, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + ) + + text_outputs: BaseModelOutputWithPooling = self.text_model( + input_ids=input_ids, + attention_mask=attention_mask, + position_ids=position_ids, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + ) + + image_embeds = vision_outputs.pooler_output + text_embeds = text_outputs.pooler_output + + # normalized features + image_embeds = image_embeds / image_embeds.norm(p=2, dim=-1, keepdim=True) + text_embeds = text_embeds / text_embeds.norm(p=2, dim=-1, keepdim=True) + + # cosine similarity as logits + logits_per_text = torch.matmul(text_embeds, image_embeds.t().to(text_embeds.device)) + + logit_scale, logit_bias = self.logit_scale.to(text_embeds.device), self.logit_bias.to(text_embeds.device) + logits_per_text = logits_per_text * logit_scale.exp() + logit_bias + + logits_per_image = logits_per_text.t() + + loss = None + if return_loss: + # Adapted from https://github.com/google-research/big_vision/blob/01edb81a4716f93a48be43b3a4af14e29cdb3a7f/big_vision/trainers/proj/image_text/siglip2.py#L287 + eye = torch.eye(logits_per_text.size(0), device=logits_per_text.device) + m1_diag1 = -torch.ones_like(logits_per_text) + 2 * eye + loglik = torch.nn.functional.logsigmoid(m1_diag1 * logits_per_text) + nll = -torch.sum(loglik, dim=-1) + loss = nll.mean() + + return Siglip2Output( + loss=loss, + logits_per_image=logits_per_image, + logits_per_text=logits_per_text, + text_embeds=text_embeds, + image_embeds=image_embeds, + text_model_output=text_outputs, + vision_model_output=vision_outputs, + ) + + +class Siglip2ForImageClassification(SiglipForImageClassification): + # Update: add `spatial_shapes` and `pixel_attention_mask` + def forward( + self, + pixel_values: torch.Tensor | None = None, + pixel_attention_mask: torch.Tensor | None = None, + spatial_shapes: torch.LongTensor | None = None, + labels: torch.Tensor | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + **kwargs, + ) -> ImageClassifierOutput: + r""" + pixel_attention_mask (`torch.Tensor` of shape `(batch_size, image_size, image_size)`, *optional*): + Mask to avoid performing attention on padding pixel indices. + spatial_shapes (`torch.LongTensor` of shape `(batch_size, 2)`): + Tensor containing the spatial dimensions (height, width) of the input images. + labels (`torch.LongTensor` of shape `(batch_size,)`, *optional*): + Labels for computing the image classification/regression loss. Indices should be in `[0, ..., + config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If + `config.num_labels > 1` a classification loss is computed (Cross-Entropy). + + Examples: + + ```python + >>> from transformers import AutoImageProcessor, Siglip2ForImageClassification + >>> import torch + >>> from PIL import Image + >>> import httpx + >>> from io import BytesIO + + >>> torch.manual_seed(3) # doctest: +IGNORE_RESULT + >>> url = "http://images.cocodataset.org/val2017/000000039769.jpg" + >>> with httpx.stream("GET", url) as response: + ... image = Image.open(BytesIO(response.read())) + + >>> # note: we are loading a `Siglip2Model` from the hub here, + >>> # so the head will be randomly initialized, hence the predictions will be random if seed is not set above. + >>> image_processor = AutoImageProcessor.from_pretrained("google/siglip2-base-patch16-224") + >>> model = Siglip2ForImageClassification.from_pretrained("google/siglip2-base-patch16-224") + + >>> inputs = image_processor(images=image, return_tensors="pt") + >>> outputs = model(**inputs) + >>> logits = outputs.logits + >>> # model predicts one of the two classes + >>> predicted_class_idx = logits.argmax(-1).item() + >>> print("Predicted class:", model.config.id2label[predicted_class_idx]) + Predicted class: LABEL_1 + ``` + """ + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + + outputs: BaseModelOutputWithPooling = self.vision_model( + pixel_values, + attention_mask=pixel_attention_mask, + spatial_shapes=spatial_shapes, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + ) + + sequence_output = outputs.last_hidden_state + + # average pool the patch tokens + if pixel_attention_mask is not None: + pool_mask = pixel_attention_mask[..., None].to(sequence_output.device) + sequence_output = torch.sum(sequence_output * pool_mask, dim=1) / torch.sum(pool_mask, dim=1) + else: + sequence_output = torch.mean(sequence_output, dim=1) + + # apply classifier + logits = self.classifier(sequence_output) + + loss = None + if labels is not None: + loss = self.loss_function(labels, logits, self.config) + + return ImageClassifierOutput( + loss=loss, + logits=logits, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + ) + + +__all__ = [ + "Siglip2Config", + "Siglip2TextConfig", + "Siglip2VisionConfig", + "Siglip2Model", + "Siglip2PreTrainedModel", + "Siglip2TextModel", + "Siglip2VisionModel", + "Siglip2ForImageClassification", + "Siglip2Tokenizer", +] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/siglip2/processing_siglip2.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/siglip2/processing_siglip2.py new file mode 100644 index 0000000000000000000000000000000000000000..2315eef2d016d7b233f032c341b0f6e6d80ff691 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/siglip2/processing_siglip2.py @@ -0,0 +1,44 @@ +# Copyright 2025 The HuggingFace Inc. team. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +""" +Image/Text processor class for SigLIP2. +""" + +from ...processing_utils import ProcessingKwargs, ProcessorMixin +from ...utils import auto_docstring + + +class Siglip2ProcessorKwargs(ProcessingKwargs, total=False): + _defaults = { + "text_kwargs": { + "padding": "max_length", + "truncation": True, + "max_length": 64, + }, + "images_kwargs": { + "max_num_patches": 256, + "patch_size": 16, + }, + } + + +@auto_docstring +class Siglip2Processor(ProcessorMixin): + valid_processor_kwargs = Siglip2ProcessorKwargs + + def __init__(self, image_processor, tokenizer): + super().__init__(image_processor, tokenizer) + + +__all__ = ["Siglip2Processor"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/siglip2/tokenization_siglip2.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/siglip2/tokenization_siglip2.py new file mode 100644 index 0000000000000000000000000000000000000000..514838cbff2f9c51e67eb8fee032e46052ccff72 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/siglip2/tokenization_siglip2.py @@ -0,0 +1,98 @@ +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# This file was automatically generated from src/transformers/models/siglip2/modular_siglip2.py. +# Do NOT edit this file manually as any edits will be overwritten by the generation of +# the file from the modular. If any change should be done, please apply the change to the +# modular_siglip2.py file directly. One of our CI enforces this. +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# Copyright 2025 The HuggingFace Inc. team. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +from tokenizers import Tokenizer, decoders, normalizers, pre_tokenizers +from tokenizers.models import BPE + +from ...tokenization_utils_tokenizers import TokenizersBackend + + +VOCAB_FILES_NAMES = {"tokenizer_file": "tokenizer.json"} + + +class Siglip2Tokenizer(TokenizersBackend): + """ + Gemma tokenizer + SigLIP2 training default: lowercase normalization. + """ + + vocab_files_names = VOCAB_FILES_NAMES + padding_side = "left" + model_input_names = ["input_ids", "attention_mask"] + model = BPE + + def __init__( + self, + vocab: str | dict[str, int] | None = None, + merges: str | list[str] | None = None, + unk_token: str = "", + bos_token: str = "", + eos_token: str = "", + pad_token: str = "", + mask_token: str = "", + **kwargs, + ): + if vocab is None: + vocab = { + str(pad_token): 0, + str(eos_token): 1, + str(bos_token): 2, + str(unk_token): 3, + str(mask_token): 4, + } + self._vocab = vocab + self._merges = merges or [] + + self._tokenizer = Tokenizer( + BPE( + vocab=self._vocab, + merges=self._merges, + fuse_unk=True, + unk_token=str(unk_token), + dropout=None, + byte_fallback=True, + ) + ) + self._tokenizer.pre_tokenizer = pre_tokenizers.Split( + pattern=" ", behavior="merged_with_previous", invert=False + ) + + self._tokenizer.decoder = decoders.Sequence( + [decoders.Replace("▁", " "), decoders.ByteFallback(), decoders.Fuse()] + ) + self._tokenizer.normalizer = normalizers.Replace(" ", "▁") + super().__init__( + unk_token=unk_token, + bos_token=bos_token, + eos_token=eos_token, + pad_token=pad_token, + mask_token=mask_token, + **kwargs, + ) + + # Persist for save/load + push_to_hub dynamic tokenizer test + if hasattr(self, "init_kwargs") and isinstance(self.init_kwargs, dict): + self.init_kwargs.setdefault("tokenizer_class", self.__class__.__name__) + + backend = getattr(self, "_tokenizer", None) + if backend is not None and backend.normalizer is not None: + backend.normalizer = normalizers.Sequence([normalizers.Lowercase(), backend.normalizer]) + + +__all__ = ["Siglip2Tokenizer"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/smollm3/__init__.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/smollm3/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..188d99ef78669b038c92223edb6b0caa4d2bb6be --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/smollm3/__init__.py @@ -0,0 +1,27 @@ +# Copyright 2025 The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from typing import TYPE_CHECKING + +from ...utils import _LazyModule +from ...utils.import_utils import define_import_structure + + +if TYPE_CHECKING: + from .configuration_smollm3 import * + from .modeling_smollm3 import * +else: + import sys + + _file = globals()["__file__"] + sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__) diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/smollm3/configuration_smollm3.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/smollm3/configuration_smollm3.py new file mode 100644 index 0000000000000000000000000000000000000000..90750cd28ea77a07c8fa4cd3a6d9fc16883c3cc1 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/smollm3/configuration_smollm3.py @@ -0,0 +1,205 @@ +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# This file was automatically generated from src/transformers/models/smollm3/modular_smollm3.py. +# Do NOT edit this file manually as any edits will be overwritten by the generation of +# the file from the modular. If any change should be done, please apply the change to the +# modular_smollm3.py file directly. One of our CI enforces this. +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# Copyright 2025 The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +from ...configuration_utils import PreTrainedConfig, layer_type_validation +from ...modeling_rope_utils import RopeParameters + + +class SmolLM3Config(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`SmolLM3Model`]. It is used to instantiate a + SmolLM3 model according to the specified arguments, defining the model architecture. Instantiating a configuration + with the defaults will yield a similar configuration to that of the SmolLM3 3B. + e.g. [HuggingFaceTB/SmolLM3-3B](https://huggingface.co/HuggingFaceTB/SmolLM3-3B) + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + vocab_size (`int`, *optional*, defaults to 128256): + Vocabulary size of the SmolLM3 model. Defines the number of different tokens that can be represented by the + `inputs_ids` passed when calling [`SmolLM3Model`] + hidden_size (`int`, *optional*, defaults to 2048): + Dimension of the hidden representations. + intermediate_size (`int`, *optional*, defaults to 11008): + Dimension of the MLP representations. + num_hidden_layers (`int`, *optional*, defaults to 36): + Number of hidden layers in the Transformer encoder. + num_attention_heads (`int`, *optional*, defaults to 16): + Number of attention heads for each attention layer in the Transformer encoder. + num_key_value_heads (`int`, *optional*, defaults to 4): + This is the number of key_value heads that should be used to implement Grouped Query Attention. If + `num_key_value_heads=num_attention_heads`, the model will use Multi Head Attention (MHA), if + `num_key_value_heads=1` the model will use Multi Query Attention (MQA) otherwise GQA is used. When + converting a multi-head checkpoint to a GQA checkpoint, each group key and value head should be constructed + by meanpooling all the original heads within that group. For more details checkout [this + paper](https://huggingface.co/papers/2305.13245). If it is not specified, will default to `16`. + hidden_act (`str` or `function`, *optional*, defaults to `"silu"`): + The non-linear activation function (function or string) in the decoder. + max_position_embeddings (`int`, *optional*, defaults to 32768): + The maximum sequence length that this model might ever be used with. + initializer_range (`float`, *optional*, defaults to 0.02): + The standard deviation of the truncated_normal_initializer for initializing all weight matrices. + rms_norm_eps (`float`, *optional*, defaults to 1e-06): + The epsilon used by the rms normalization layers. + use_cache (`bool`, *optional*, defaults to `True`): + Whether or not the model should return the last key/values attentions (not used by all models). Only + relevant if `config.is_decoder=True`. + pad_token_id (`int`, *optional*, defaults to 128004): + The id of the padding token. + bos_token_id (`int`, *optional*, defaults to 128000): + The id of the beginning of sentence token. + eos_token_id (`int`, *optional*, defaults to 128001): + The id of the end of sentence token. + rope_parameters (`RopeParameters`, *optional*): + Dictionary containing the configuration parameters for the RoPE embeddings. The dictionary should contain + a value for `rope_theta` and optionally parameters used for scaling in case you want to use RoPE + with longer `max_position_embeddings`. + use_sliding_window (`bool`, *optional*, defaults to `False`): + Whether to use sliding window attention. + sliding_window (`int`, *optional*): + Sliding window attention (SWA) window size. If not specified, will default to `None`. + no_rope_layers (`List[int]`, *optional*): + List with at least the same length as the number of layers in the model. + A `1` at an index position indicates that the corresponding layer will use RoPE, + while a `0` indicates that it's a NoPE layer. + no_rope_layer_interval (`int`, *optional*, defaults to 4): + If `no_rope_layers` is `None`, it will be created using a NoPE layer every + `no_rope_layer_interval` layers. + layer_types (`list`, *optional*): + Attention pattern for each layer. Automatically computed based on sliding window and NoPE settings. + attention_bias (`bool`, *optional*, defaults to `False`): + Whether to use a bias in the query, key, value and output projection layers during self-attention. + attention_dropout (`float`, *optional*, defaults to 0.0): + The dropout ratio for the attention probabilities. + + ```python + >>> from transformers import SmolLM3Model, SmolLM3Config + + >>> # Initializing a SmolLM3 style configuration + >>> configuration = SmolLM3Config() + + >>> # Initializing a model from the SmolLM3 style configuration + >>> model = SmolLM3Model(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "smollm3" + keys_to_ignore_at_inference = ["past_key_values"] + default_theta = 2000000.0 + + base_model_tp_plan = { + "layers.*.self_attn.q_proj": "colwise", + "layers.*.self_attn.k_proj": "colwise", + "layers.*.self_attn.v_proj": "colwise", + "layers.*.self_attn.o_proj": "rowwise", + "layers.*.mlp.gate_proj": "colwise", + "layers.*.mlp.up_proj": "colwise", + "layers.*.mlp.down_proj": "rowwise", + } + base_model_pp_plan = { + "embed_tokens": (["input_ids"], ["inputs_embeds"]), + "layers": (["hidden_states", "attention_mask"], ["hidden_states"]), + "norm": (["hidden_states"], ["hidden_states"]), + } + + def __init__( + self, + vocab_size: int | None = 128256, + hidden_size: int | None = 2048, + intermediate_size: int | None = 11008, + num_hidden_layers: int | None = 36, + num_attention_heads: int | None = 16, + num_key_value_heads: int | None = 4, + hidden_act: str | None = "silu", + max_position_embeddings: int | None = 32768, + initializer_range: float | None = 0.02, + rms_norm_eps: int | None = 1e-6, + use_cache: bool | None = True, + pad_token_id: int | None = 128004, + bos_token_id: int | None = 128000, + eos_token_id: int | None = 128001, + rope_parameters: RopeParameters | dict[str, RopeParameters] | None = None, + use_sliding_window: bool | None = False, + sliding_window: int | None = None, + no_rope_layers: int | None = None, + no_rope_layer_interval: int | None = 4, + layer_types: int | None = None, + attention_bias: bool | None = False, + attention_dropout: float | None = 0.0, + mlp_bias: bool | None = False, + tie_word_embeddings: bool | None = True, + **kwargs, + ): + self.pad_token_id = pad_token_id + self.bos_token_id = bos_token_id + self.eos_token_id = eos_token_id + self.tie_word_embeddings = tie_word_embeddings + self.vocab_size = vocab_size + self.max_position_embeddings = max_position_embeddings + self.mlp_bias = mlp_bias + self.hidden_size = hidden_size + self.intermediate_size = intermediate_size + self.num_hidden_layers = num_hidden_layers + self.num_attention_heads = num_attention_heads + self.use_sliding_window = use_sliding_window + self.sliding_window = sliding_window + + # for backward compatibility + if num_key_value_heads is None: + num_key_value_heads = num_attention_heads + + self.num_key_value_heads = num_key_value_heads + self.hidden_act = hidden_act + self.initializer_range = initializer_range + self.rms_norm_eps = rms_norm_eps + self.use_cache = use_cache + self.attention_bias = attention_bias + self.attention_dropout = attention_dropout + + if no_rope_layers is None: + self.no_rope_layers = [ + int((layer_idx + 1) % no_rope_layer_interval != 0) for layer_idx in range(num_hidden_layers) + ] + else: + self.no_rope_layers = no_rope_layers + + self.no_rope_layer_interval = no_rope_layer_interval + + # Update layer_types based on sliding window and NoPE pattern + if layer_types is None: + layer_types = [] + for layer_idx in range(num_hidden_layers): + has_rope = self.no_rope_layers[layer_idx] + if use_sliding_window and sliding_window is not None and not has_rope: + layer_types.append("sliding_attention") + else: + layer_types.append("full_attention") + + self.layer_types = layer_types + layer_type_validation(self.layer_types, self.num_hidden_layers) + + self.rope_parameters = rope_parameters + super().__init__(**kwargs) + + +__all__ = ["SmolLM3Config"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/smollm3/modeling_smollm3.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/smollm3/modeling_smollm3.py new file mode 100644 index 0000000000000000000000000000000000000000..1a771ccfccefb8802e366f9ba86de312382b21d0 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/smollm3/modeling_smollm3.py @@ -0,0 +1,552 @@ +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# This file was automatically generated from src/transformers/models/smollm3/modular_smollm3.py. +# Do NOT edit this file manually as any edits will be overwritten by the generation of +# the file from the modular. If any change should be done, please apply the change to the +# modular_smollm3.py file directly. One of our CI enforces this. +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# Copyright 2025 The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +from collections.abc import Callable +from typing import Optional + +import torch +from torch import nn + +from ...activations import ACT2FN +from ...cache_utils import Cache, DynamicCache +from ...generation import GenerationMixin +from ...integrations import use_kernel_forward_from_hub, use_kernel_func_from_hub, use_kernelized_func +from ...masking_utils import create_causal_mask, create_sliding_window_causal_mask +from ...modeling_flash_attention_utils import FlashAttentionKwargs +from ...modeling_layers import ( + GenericForQuestionAnswering, + GenericForSequenceClassification, + GenericForTokenClassification, + GradientCheckpointingLayer, +) +from ...modeling_outputs import BaseModelOutputWithPast, CausalLMOutputWithPast +from ...modeling_rope_utils import ROPE_INIT_FUNCTIONS, dynamic_rope_update +from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel +from ...processing_utils import Unpack +from ...utils import TransformersKwargs, auto_docstring, can_return_tuple +from ...utils.generic import maybe_autocast, merge_with_config_defaults +from ...utils.output_capturing import capture_outputs +from .configuration_smollm3 import SmolLM3Config + + +class SmolLM3RotaryEmbedding(nn.Module): + inv_freq: torch.Tensor # fix linting for `register_buffer` + + def __init__(self, config: SmolLM3Config, device=None): + super().__init__() + self.max_seq_len_cached = config.max_position_embeddings + self.original_max_seq_len = config.max_position_embeddings + + self.config = config + + self.rope_type = self.config.rope_parameters["rope_type"] + rope_init_fn: Callable = self.compute_default_rope_parameters + if self.rope_type != "default": + rope_init_fn = ROPE_INIT_FUNCTIONS[self.rope_type] + inv_freq, self.attention_scaling = rope_init_fn(self.config, device) + + self.register_buffer("inv_freq", inv_freq, persistent=False) + self.register_buffer("original_inv_freq", inv_freq.clone(), persistent=False) + + @staticmethod + def compute_default_rope_parameters( + config: SmolLM3Config | None = None, + device: Optional["torch.device"] = None, + seq_len: int | None = None, + ) -> tuple["torch.Tensor", float]: + """ + Computes the inverse frequencies according to the original RoPE implementation + Args: + config ([`~transformers.PreTrainedConfig`]): + The model configuration. + device (`torch.device`): + The device to use for initialization of the inverse frequencies. + seq_len (`int`, *optional*): + The current sequence length. Unused for this type of RoPE. + Returns: + Tuple of (`torch.Tensor`, `float`), containing the inverse frequencies for the RoPE embeddings and the + post-processing scaling factor applied to the computed cos/sin (unused in this type of RoPE). + """ + base = config.rope_parameters["rope_theta"] + dim = getattr(config, "head_dim", None) or config.hidden_size // config.num_attention_heads + + attention_factor = 1.0 # Unused in this type of RoPE + + # Compute the inverse frequencies + inv_freq = 1.0 / ( + base ** (torch.arange(0, dim, 2, dtype=torch.int64).to(device=device, dtype=torch.float) / dim) + ) + return inv_freq, attention_factor + + @torch.no_grad() + @dynamic_rope_update # power user: used with advanced RoPE types (e.g. dynamic rope) + def forward(self, x, position_ids): + inv_freq_expanded = self.inv_freq[None, :, None].float().expand(position_ids.shape[0], -1, 1).to(x.device) + position_ids_expanded = position_ids[:, None, :].float() + + device_type = x.device.type if isinstance(x.device.type, str) and x.device.type != "mps" else "cpu" + with maybe_autocast(device_type=device_type, enabled=False): # Force float32 + freqs = (inv_freq_expanded.float() @ position_ids_expanded.float()).transpose(1, 2) + emb = torch.cat((freqs, freqs), dim=-1) + cos = emb.cos() * self.attention_scaling + sin = emb.sin() * self.attention_scaling + + return cos.to(dtype=x.dtype), sin.to(dtype=x.dtype) + + +def rotate_half(x): + """Rotates half the hidden dims of the input.""" + x1 = x[..., : x.shape[-1] // 2] + x2 = x[..., x.shape[-1] // 2 :] + return torch.cat((-x2, x1), dim=-1) + + +@use_kernel_func_from_hub("rotary_pos_emb") +def apply_rotary_pos_emb(q, k, cos, sin, unsqueeze_dim=1): + """Applies Rotary Position Embedding to the query and key tensors. + + Args: + q (`torch.Tensor`): The query tensor. + k (`torch.Tensor`): The key tensor. + cos (`torch.Tensor`): The cosine part of the rotary embedding. + sin (`torch.Tensor`): The sine part of the rotary embedding. + unsqueeze_dim (`int`, *optional*, defaults to 1): + The 'unsqueeze_dim' argument specifies the dimension along which to unsqueeze cos[position_ids] and + sin[position_ids] so that they can be properly broadcasted to the dimensions of q and k. For example, note + that cos[position_ids] and sin[position_ids] have the shape [batch_size, seq_len, head_dim]. Then, if q and + k have the shape [batch_size, heads, seq_len, head_dim], then setting unsqueeze_dim=1 makes + cos[position_ids] and sin[position_ids] broadcastable to the shapes of q and k. Similarly, if q and k have + the shape [batch_size, seq_len, heads, head_dim], then set unsqueeze_dim=2. + Returns: + `tuple(torch.Tensor)` comprising of the query and key tensors rotated using the Rotary Position Embedding. + """ + cos = cos.unsqueeze(unsqueeze_dim) + sin = sin.unsqueeze(unsqueeze_dim) + q_embed = (q * cos) + (rotate_half(q) * sin) + k_embed = (k * cos) + (rotate_half(k) * sin) + return q_embed, k_embed + + +def repeat_kv(hidden_states: torch.Tensor, n_rep: int) -> torch.Tensor: + """ + This is the equivalent of torch.repeat_interleave(x, dim=1, repeats=n_rep). The hidden states go from (batch, + num_key_value_heads, seqlen, head_dim) to (batch, num_attention_heads, seqlen, head_dim) + """ + batch, num_key_value_heads, slen, head_dim = hidden_states.shape + if n_rep == 1: + return hidden_states + hidden_states = hidden_states[:, :, None, :, :].expand(batch, num_key_value_heads, n_rep, slen, head_dim) + return hidden_states.reshape(batch, num_key_value_heads * n_rep, slen, head_dim) + + +def eager_attention_forward( + module: nn.Module, + query: torch.Tensor, + key: torch.Tensor, + value: torch.Tensor, + attention_mask: torch.Tensor | None, + scaling: float, + dropout: float = 0.0, + **kwargs: Unpack[TransformersKwargs], +): + key_states = repeat_kv(key, module.num_key_value_groups) + value_states = repeat_kv(value, module.num_key_value_groups) + + attn_weights = torch.matmul(query, key_states.transpose(2, 3)) * scaling + if attention_mask is not None: + attn_weights = attn_weights + attention_mask + + attn_weights = nn.functional.softmax(attn_weights, dim=-1, dtype=torch.float32).to(query.dtype) + attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training) + attn_output = torch.matmul(attn_weights, value_states) + attn_output = attn_output.transpose(1, 2).contiguous() + + return attn_output, attn_weights + + +@use_kernelized_func(apply_rotary_pos_emb) +class SmolLM3Attention(nn.Module): + """Multi-headed attention from 'Attention Is All You Need' paper""" + + def __init__(self, config: SmolLM3Config, layer_idx: int): + super().__init__() + self.config = config + self.layer_idx = layer_idx + self.head_dim = getattr(config, "head_dim", config.hidden_size // config.num_attention_heads) + self.num_key_value_groups = config.num_attention_heads // config.num_key_value_heads + self.scaling = self.head_dim**-0.5 + self.attention_dropout = config.attention_dropout + self.is_causal = True + + self.q_proj = nn.Linear( + config.hidden_size, config.num_attention_heads * self.head_dim, bias=config.attention_bias + ) + self.k_proj = nn.Linear( + config.hidden_size, config.num_key_value_heads * self.head_dim, bias=config.attention_bias + ) + self.v_proj = nn.Linear( + config.hidden_size, config.num_key_value_heads * self.head_dim, bias=config.attention_bias + ) + self.o_proj = nn.Linear( + config.num_attention_heads * self.head_dim, config.hidden_size, bias=config.attention_bias + ) + + self.use_rope = config.no_rope_layers[layer_idx] + self.sliding_window = ( + config.sliding_window + if config.use_sliding_window and config.layer_types[layer_idx] == "sliding_attention" + else None + ) + + def forward( + self, + hidden_states: torch.Tensor, + position_embeddings: tuple[torch.Tensor, torch.Tensor], + attention_mask: torch.Tensor | None, + past_key_values: Cache | None = None, + cache_position: torch.LongTensor | None = None, + **kwargs: Unpack[FlashAttentionKwargs], + ) -> tuple[torch.Tensor, torch.Tensor | None]: + input_shape = hidden_states.shape[:-1] + hidden_shape = (*input_shape, -1, self.head_dim) + + query_states = self.q_proj(hidden_states).view(hidden_shape).transpose(1, 2) + key_states = self.k_proj(hidden_states).view(hidden_shape).transpose(1, 2) + value_states = self.v_proj(hidden_states).view(hidden_shape).transpose(1, 2) + + if self.use_rope: + cos, sin = position_embeddings + query_states, key_states = apply_rotary_pos_emb(query_states, key_states, cos, sin) + + if past_key_values is not None: + cache_kwargs = {"cache_position": cache_position} + key_states, value_states = past_key_values.update(key_states, value_states, self.layer_idx, cache_kwargs) + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, eager_attention_forward + ) + + attn_output, attn_weights = attention_interface( + self, + query_states, + key_states, + value_states, + attention_mask, + dropout=0.0 if not self.training else self.attention_dropout, + scaling=self.scaling, + sliding_window=self.sliding_window, + **kwargs, + ) + + attn_output = attn_output.reshape(*input_shape, -1).contiguous() + attn_output = self.o_proj(attn_output) + return attn_output, attn_weights + + +@use_kernel_forward_from_hub("RMSNorm") +class SmolLM3RMSNorm(nn.Module): + def __init__(self, hidden_size, eps: float = 1e-6) -> None: + """ + SmolLM3RMSNorm is equivalent to T5LayerNorm + """ + super().__init__() + self.weight = nn.Parameter(torch.ones(hidden_size)) + self.variance_epsilon = eps + + def forward(self, hidden_states: torch.Tensor) -> torch.Tensor: + input_dtype = hidden_states.dtype + hidden_states = hidden_states.to(torch.float32) + variance = hidden_states.pow(2).mean(-1, keepdim=True) + hidden_states = hidden_states * torch.rsqrt(variance + self.variance_epsilon) + return self.weight * hidden_states.to(input_dtype) + + def extra_repr(self): + return f"{tuple(self.weight.shape)}, eps={self.variance_epsilon}" + + +class SmolLM3MLP(nn.Module): + def __init__(self, config): + super().__init__() + self.config = config + self.hidden_size = config.hidden_size + self.intermediate_size = config.intermediate_size + self.gate_proj = nn.Linear(self.hidden_size, self.intermediate_size, bias=config.mlp_bias) + self.up_proj = nn.Linear(self.hidden_size, self.intermediate_size, bias=config.mlp_bias) + self.down_proj = nn.Linear(self.intermediate_size, self.hidden_size, bias=config.mlp_bias) + self.act_fn = ACT2FN[config.hidden_act] + + def forward(self, x): + down_proj = self.down_proj(self.act_fn(self.gate_proj(x)) * self.up_proj(x)) + return down_proj + + +class SmolLM3DecoderLayer(GradientCheckpointingLayer): + def __init__(self, config: SmolLM3Config, layer_idx: int): + super().__init__() + self.hidden_size = config.hidden_size + + self.self_attn = SmolLM3Attention(config=config, layer_idx=layer_idx) + + self.mlp = SmolLM3MLP(config) + self.input_layernorm = SmolLM3RMSNorm(config.hidden_size, eps=config.rms_norm_eps) + self.post_attention_layernorm = SmolLM3RMSNorm(config.hidden_size, eps=config.rms_norm_eps) + self.attention_type = config.layer_types[layer_idx] + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.Tensor | None = None, + position_ids: torch.LongTensor | None = None, + past_key_values: Cache | None = None, + use_cache: bool | None = False, + cache_position: torch.LongTensor | None = None, + position_embeddings: tuple[torch.Tensor, torch.Tensor] | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> torch.Tensor: + residual = hidden_states + hidden_states = self.input_layernorm(hidden_states) + # Self Attention + hidden_states, _ = self.self_attn( + hidden_states=hidden_states, + attention_mask=attention_mask, + position_ids=position_ids, + past_key_values=past_key_values, + use_cache=use_cache, + cache_position=cache_position, + position_embeddings=position_embeddings, + **kwargs, + ) + hidden_states = residual + hidden_states + + # Fully Connected + residual = hidden_states + hidden_states = self.post_attention_layernorm(hidden_states) + hidden_states = self.mlp(hidden_states) + hidden_states = residual + hidden_states + return hidden_states + + +@auto_docstring +class SmolLM3PreTrainedModel(PreTrainedModel): + config: SmolLM3Config + base_model_prefix = "model" + supports_gradient_checkpointing = True + _no_split_modules = ["SmolLM3DecoderLayer"] + _skip_keys_device_placement = ["past_key_values"] + _supports_flash_attn = True + _supports_sdpa = True + _supports_flex_attn = True + + _can_compile_fullgraph = True + _supports_attention_backend = True + _can_record_outputs = { + "hidden_states": SmolLM3DecoderLayer, + "attentions": SmolLM3Attention, + } + + +@auto_docstring +class SmolLM3Model(SmolLM3PreTrainedModel): + def __init__(self, config: SmolLM3Config): + super().__init__(config) + self.padding_idx = config.pad_token_id + self.vocab_size = config.vocab_size + + self.embed_tokens = nn.Embedding(config.vocab_size, config.hidden_size, self.padding_idx) + self.layers = nn.ModuleList( + [SmolLM3DecoderLayer(config, layer_idx) for layer_idx in range(config.num_hidden_layers)] + ) + self.norm = SmolLM3RMSNorm(config.hidden_size, eps=config.rms_norm_eps) + self.rotary_emb = SmolLM3RotaryEmbedding(config=config) + self.gradient_checkpointing = False + self.has_sliding_layers = "sliding_attention" in self.config.layer_types + + # Initialize weights and apply final processing + self.post_init() + + @merge_with_config_defaults + @capture_outputs + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.Tensor | None = None, + position_ids: torch.LongTensor | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.FloatTensor | None = None, + use_cache: bool | None = None, + cache_position: torch.LongTensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> BaseModelOutputWithPast: + if (input_ids is None) ^ (inputs_embeds is not None): + raise ValueError("You must specify exactly one of input_ids or inputs_embeds") + + if inputs_embeds is None: + inputs_embeds = self.embed_tokens(input_ids) + + if use_cache and past_key_values is None: + past_key_values = DynamicCache(config=self.config) + + if cache_position is None: + past_seen_tokens = past_key_values.get_seq_length() if past_key_values is not None else 0 + cache_position = torch.arange( + past_seen_tokens, past_seen_tokens + inputs_embeds.shape[1], device=inputs_embeds.device + ) + + if position_ids is None: + position_ids = cache_position.unsqueeze(0) + + # It may already have been prepared by e.g. `generate` + if not isinstance(causal_mask_mapping := attention_mask, dict): + # Prepare mask arguments + mask_kwargs = { + "config": self.config, + "inputs_embeds": inputs_embeds, + "attention_mask": attention_mask, + "cache_position": cache_position, + "past_key_values": past_key_values, + "position_ids": position_ids, + } + # Create the masks + causal_mask_mapping = { + "full_attention": create_causal_mask(**mask_kwargs), + } + # The sliding window alternating layers are not always activated depending on the config + if self.has_sliding_layers: + causal_mask_mapping["sliding_attention"] = create_sliding_window_causal_mask(**mask_kwargs) + + hidden_states = inputs_embeds + position_embeddings = self.rotary_emb(hidden_states, position_ids) + + for decoder_layer in self.layers[: self.config.num_hidden_layers]: + hidden_states = decoder_layer( + hidden_states, + attention_mask=causal_mask_mapping[decoder_layer.attention_type], + position_embeddings=position_embeddings, + position_ids=position_ids, + past_key_values=past_key_values, + use_cache=use_cache, + cache_position=cache_position, + **kwargs, + ) + + hidden_states = self.norm(hidden_states) + return BaseModelOutputWithPast( + last_hidden_state=hidden_states, + past_key_values=past_key_values if use_cache else None, + ) + + +@auto_docstring +class SmolLM3ForCausalLM(SmolLM3PreTrainedModel, GenerationMixin): + _tied_weights_keys = {"lm_head.weight": "model.embed_tokens.weight"} + _tp_plan = {"lm_head": "colwise_gather_output"} + _pp_plan = {"lm_head": (["hidden_states"], ["logits"])} + + def __init__(self, config): + super().__init__(config) + self.model = SmolLM3Model(config) + self.vocab_size = config.vocab_size + self.lm_head = nn.Linear(config.hidden_size, config.vocab_size, bias=False) + + # Initialize weights and apply final processing + self.post_init() + + @can_return_tuple + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.Tensor | None = None, + position_ids: torch.LongTensor | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.FloatTensor | None = None, + labels: torch.LongTensor | None = None, + use_cache: bool | None = None, + cache_position: torch.LongTensor | None = None, + logits_to_keep: int | torch.Tensor = 0, + **kwargs: Unpack[TransformersKwargs], + ) -> CausalLMOutputWithPast: + r""" + Example: + + ```python + >>> from transformers import AutoTokenizer, SmolLM3ForCausalLM + + >>> model = SmolLM3ForCausalLM.from_pretrained("meta-smollm3/SmolLM3-2-7b-hf") + >>> tokenizer = AutoTokenizer.from_pretrained("meta-smollm3/SmolLM3-2-7b-hf") + + >>> prompt = "Hey, are you conscious? Can you talk to me?" + >>> inputs = tokenizer(prompt, return_tensors="pt") + + >>> # Generate + >>> generate_ids = model.generate(inputs.input_ids, max_length=30) + >>> tokenizer.batch_decode(generate_ids, skip_special_tokens=True, clean_up_tokenization_spaces=False)[0] + "Hey, are you conscious? Can you talk to me?\nI'm not conscious, but I can talk to you." + ```""" + outputs: BaseModelOutputWithPast = self.model( + input_ids=input_ids, + attention_mask=attention_mask, + position_ids=position_ids, + past_key_values=past_key_values, + inputs_embeds=inputs_embeds, + use_cache=use_cache, + cache_position=cache_position, + **kwargs, + ) + + hidden_states = outputs.last_hidden_state + # Only compute necessary logits, and do not upcast them to float if we are not computing the loss + slice_indices = slice(-logits_to_keep, None) if isinstance(logits_to_keep, int) else logits_to_keep + logits = self.lm_head(hidden_states[:, slice_indices, :]) + + loss = None + if labels is not None: + loss = self.loss_function(logits=logits, labels=labels, vocab_size=self.config.vocab_size, **kwargs) + + return CausalLMOutputWithPast( + loss=loss, + logits=logits, + past_key_values=outputs.past_key_values, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + ) + + +class SmolLM3ForSequenceClassification(GenericForSequenceClassification, SmolLM3PreTrainedModel): + pass + + +class SmolLM3ForTokenClassification(GenericForTokenClassification, SmolLM3PreTrainedModel): + pass + + +class SmolLM3ForQuestionAnswering(GenericForQuestionAnswering, SmolLM3PreTrainedModel): + base_model_prefix = "transformer" # For BC, where `transformer` was used instead of `model` + + +__all__ = [ + "SmolLM3PreTrainedModel", + "SmolLM3Model", + "SmolLM3ForCausalLM", + "SmolLM3ForSequenceClassification", + "SmolLM3ForTokenClassification", + "SmolLM3ForQuestionAnswering", +] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/smollm3/modular_smollm3.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/smollm3/modular_smollm3.py new file mode 100644 index 0000000000000000000000000000000000000000..b0c7af7c3c22d398cf0a9532b36b9e255d28a7ef --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/smollm3/modular_smollm3.py @@ -0,0 +1,321 @@ +# Copyright 2025 The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +from collections.abc import Callable + +import torch + +from ...cache_utils import Cache +from ...configuration_utils import PreTrainedConfig, layer_type_validation +from ...modeling_flash_attention_utils import FlashAttentionKwargs +from ...modeling_rope_utils import RopeParameters +from ...modeling_utils import ALL_ATTENTION_FUNCTIONS +from ...processing_utils import Unpack +from ...utils import logging +from ..llama.modeling_llama import ( + LlamaAttention, + LlamaDecoderLayer, + LlamaForCausalLM, + LlamaForQuestionAnswering, + LlamaForSequenceClassification, + LlamaForTokenClassification, + LlamaPreTrainedModel, + apply_rotary_pos_emb, + eager_attention_forward, +) +from ..qwen2.modeling_qwen2 import Qwen2Model, Qwen2RotaryEmbedding + + +logger = logging.get_logger(__name__) + + +class SmolLM3Config(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`SmolLM3Model`]. It is used to instantiate a + SmolLM3 model according to the specified arguments, defining the model architecture. Instantiating a configuration + with the defaults will yield a similar configuration to that of the SmolLM3 3B. + e.g. [HuggingFaceTB/SmolLM3-3B](https://huggingface.co/HuggingFaceTB/SmolLM3-3B) + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + vocab_size (`int`, *optional*, defaults to 128256): + Vocabulary size of the SmolLM3 model. Defines the number of different tokens that can be represented by the + `inputs_ids` passed when calling [`SmolLM3Model`] + hidden_size (`int`, *optional*, defaults to 2048): + Dimension of the hidden representations. + intermediate_size (`int`, *optional*, defaults to 11008): + Dimension of the MLP representations. + num_hidden_layers (`int`, *optional*, defaults to 36): + Number of hidden layers in the Transformer encoder. + num_attention_heads (`int`, *optional*, defaults to 16): + Number of attention heads for each attention layer in the Transformer encoder. + num_key_value_heads (`int`, *optional*, defaults to 4): + This is the number of key_value heads that should be used to implement Grouped Query Attention. If + `num_key_value_heads=num_attention_heads`, the model will use Multi Head Attention (MHA), if + `num_key_value_heads=1` the model will use Multi Query Attention (MQA) otherwise GQA is used. When + converting a multi-head checkpoint to a GQA checkpoint, each group key and value head should be constructed + by meanpooling all the original heads within that group. For more details checkout [this + paper](https://huggingface.co/papers/2305.13245). If it is not specified, will default to `16`. + hidden_act (`str` or `function`, *optional*, defaults to `"silu"`): + The non-linear activation function (function or string) in the decoder. + max_position_embeddings (`int`, *optional*, defaults to 32768): + The maximum sequence length that this model might ever be used with. + initializer_range (`float`, *optional*, defaults to 0.02): + The standard deviation of the truncated_normal_initializer for initializing all weight matrices. + rms_norm_eps (`float`, *optional*, defaults to 1e-06): + The epsilon used by the rms normalization layers. + use_cache (`bool`, *optional*, defaults to `True`): + Whether or not the model should return the last key/values attentions (not used by all models). Only + relevant if `config.is_decoder=True`. + pad_token_id (`int`, *optional*, defaults to 128004): + The id of the padding token. + bos_token_id (`int`, *optional*, defaults to 128000): + The id of the beginning of sentence token. + eos_token_id (`int`, *optional*, defaults to 128001): + The id of the end of sentence token. + rope_parameters (`RopeParameters`, *optional*): + Dictionary containing the configuration parameters for the RoPE embeddings. The dictionary should contain + a value for `rope_theta` and optionally parameters used for scaling in case you want to use RoPE + with longer `max_position_embeddings`. + use_sliding_window (`bool`, *optional*, defaults to `False`): + Whether to use sliding window attention. + sliding_window (`int`, *optional*): + Sliding window attention (SWA) window size. If not specified, will default to `None`. + no_rope_layers (`List[int]`, *optional*): + List with at least the same length as the number of layers in the model. + A `1` at an index position indicates that the corresponding layer will use RoPE, + while a `0` indicates that it's a NoPE layer. + no_rope_layer_interval (`int`, *optional*, defaults to 4): + If `no_rope_layers` is `None`, it will be created using a NoPE layer every + `no_rope_layer_interval` layers. + layer_types (`list`, *optional*): + Attention pattern for each layer. Automatically computed based on sliding window and NoPE settings. + attention_bias (`bool`, *optional*, defaults to `False`): + Whether to use a bias in the query, key, value and output projection layers during self-attention. + attention_dropout (`float`, *optional*, defaults to 0.0): + The dropout ratio for the attention probabilities. + + ```python + >>> from transformers import SmolLM3Model, SmolLM3Config + + >>> # Initializing a SmolLM3 style configuration + >>> configuration = SmolLM3Config() + + >>> # Initializing a model from the SmolLM3 style configuration + >>> model = SmolLM3Model(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "smollm3" + keys_to_ignore_at_inference = ["past_key_values"] + default_theta = 2000000.0 + + base_model_tp_plan = { + "layers.*.self_attn.q_proj": "colwise", + "layers.*.self_attn.k_proj": "colwise", + "layers.*.self_attn.v_proj": "colwise", + "layers.*.self_attn.o_proj": "rowwise", + "layers.*.mlp.gate_proj": "colwise", + "layers.*.mlp.up_proj": "colwise", + "layers.*.mlp.down_proj": "rowwise", + } + base_model_pp_plan = { + "embed_tokens": (["input_ids"], ["inputs_embeds"]), + "layers": (["hidden_states", "attention_mask"], ["hidden_states"]), + "norm": (["hidden_states"], ["hidden_states"]), + } + + def __init__( + self, + vocab_size: int | None = 128256, + hidden_size: int | None = 2048, + intermediate_size: int | None = 11008, + num_hidden_layers: int | None = 36, + num_attention_heads: int | None = 16, + num_key_value_heads: int | None = 4, + hidden_act: str | None = "silu", + max_position_embeddings: int | None = 32768, + initializer_range: float | None = 0.02, + rms_norm_eps: int | None = 1e-6, + use_cache: bool | None = True, + pad_token_id: int | None = 128004, + bos_token_id: int | None = 128000, + eos_token_id: int | None = 128001, + rope_parameters: RopeParameters | dict[str, RopeParameters] | None = None, + use_sliding_window: bool | None = False, + sliding_window: int | None = None, + no_rope_layers: int | None = None, + no_rope_layer_interval: int | None = 4, + layer_types: int | None = None, + attention_bias: bool | None = False, + attention_dropout: float | None = 0.0, + mlp_bias: bool | None = False, + tie_word_embeddings: bool | None = True, + **kwargs, + ): + self.pad_token_id = pad_token_id + self.bos_token_id = bos_token_id + self.eos_token_id = eos_token_id + self.tie_word_embeddings = tie_word_embeddings + self.vocab_size = vocab_size + self.max_position_embeddings = max_position_embeddings + self.mlp_bias = mlp_bias + self.hidden_size = hidden_size + self.intermediate_size = intermediate_size + self.num_hidden_layers = num_hidden_layers + self.num_attention_heads = num_attention_heads + self.use_sliding_window = use_sliding_window + self.sliding_window = sliding_window + + # for backward compatibility + if num_key_value_heads is None: + num_key_value_heads = num_attention_heads + + self.num_key_value_heads = num_key_value_heads + self.hidden_act = hidden_act + self.initializer_range = initializer_range + self.rms_norm_eps = rms_norm_eps + self.use_cache = use_cache + self.attention_bias = attention_bias + self.attention_dropout = attention_dropout + + if no_rope_layers is None: + self.no_rope_layers = [ + int((layer_idx + 1) % no_rope_layer_interval != 0) for layer_idx in range(num_hidden_layers) + ] + else: + self.no_rope_layers = no_rope_layers + + self.no_rope_layer_interval = no_rope_layer_interval + + # Update layer_types based on sliding window and NoPE pattern + if layer_types is None: + layer_types = [] + for layer_idx in range(num_hidden_layers): + has_rope = self.no_rope_layers[layer_idx] + if use_sliding_window and sliding_window is not None and not has_rope: + layer_types.append("sliding_attention") + else: + layer_types.append("full_attention") + + self.layer_types = layer_types + layer_type_validation(self.layer_types, self.num_hidden_layers) + + self.rope_parameters = rope_parameters + super().__init__(**kwargs) + + +class SmolLM3RotaryEmbedding(Qwen2RotaryEmbedding): + pass + + +class SmolLM3Attention(LlamaAttention): + def __init__(self, config: SmolLM3Config, layer_idx: int): + super().__init__(config, layer_idx) + + self.use_rope = config.no_rope_layers[layer_idx] + self.sliding_window = ( + config.sliding_window + if config.use_sliding_window and config.layer_types[layer_idx] == "sliding_attention" + else None + ) + + def forward( + self, + hidden_states: torch.Tensor, + position_embeddings: tuple[torch.Tensor, torch.Tensor], + attention_mask: torch.Tensor | None, + past_key_values: Cache | None = None, + cache_position: torch.LongTensor | None = None, + **kwargs: Unpack[FlashAttentionKwargs], + ) -> tuple[torch.Tensor, torch.Tensor | None]: + input_shape = hidden_states.shape[:-1] + hidden_shape = (*input_shape, -1, self.head_dim) + + query_states = self.q_proj(hidden_states).view(hidden_shape).transpose(1, 2) + key_states = self.k_proj(hidden_states).view(hidden_shape).transpose(1, 2) + value_states = self.v_proj(hidden_states).view(hidden_shape).transpose(1, 2) + + if self.use_rope: + cos, sin = position_embeddings + query_states, key_states = apply_rotary_pos_emb(query_states, key_states, cos, sin) + + if past_key_values is not None: + cache_kwargs = {"cache_position": cache_position} + key_states, value_states = past_key_values.update(key_states, value_states, self.layer_idx, cache_kwargs) + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, eager_attention_forward + ) + + attn_output, attn_weights = attention_interface( + self, + query_states, + key_states, + value_states, + attention_mask, + dropout=0.0 if not self.training else self.attention_dropout, + scaling=self.scaling, + sliding_window=self.sliding_window, + **kwargs, + ) + + attn_output = attn_output.reshape(*input_shape, -1).contiguous() + attn_output = self.o_proj(attn_output) + return attn_output, attn_weights + + +class SmolLM3DecoderLayer(LlamaDecoderLayer): + def __init__(self, config: SmolLM3Config, layer_idx: int): + super().__init__(config, layer_idx) + self.attention_type = config.layer_types[layer_idx] + + +class SmolLM3PreTrainedModel(LlamaPreTrainedModel): + pass + + +class SmolLM3Model(Qwen2Model): + pass + + +class SmolLM3ForCausalLM(LlamaForCausalLM): + pass + + +class SmolLM3ForSequenceClassification(LlamaForSequenceClassification): + pass + + +class SmolLM3ForTokenClassification(LlamaForTokenClassification): + pass + + +class SmolLM3ForQuestionAnswering(LlamaForQuestionAnswering): + pass + + +__all__ = [ + "SmolLM3Config", + "SmolLM3PreTrainedModel", + "SmolLM3Model", + "SmolLM3ForCausalLM", + "SmolLM3ForSequenceClassification", + "SmolLM3ForTokenClassification", + "SmolLM3ForQuestionAnswering", +] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/smolvlm/__init__.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/smolvlm/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..5205a84b25c45f7f378d22808f1a307afb58c909 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/smolvlm/__init__.py @@ -0,0 +1,30 @@ +# Copyright 2025 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +from typing import TYPE_CHECKING + +from ...utils import _LazyModule +from ...utils.import_utils import define_import_structure + + +if TYPE_CHECKING: + from .configuration_smolvlm import * + from .image_processing_smolvlm import * + from .image_processing_smolvlm_fast import * + from .modeling_smolvlm import * + from .processing_smolvlm import * +else: + import sys + + _file = globals()["__file__"] + sys.modules[__name__] = _LazyModule(__name__, _file, define_import_structure(_file), module_spec=__spec__) diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/smolvlm/configuration_smolvlm.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/smolvlm/configuration_smolvlm.py new file mode 100644 index 0000000000000000000000000000000000000000..c73331f0af1196757dffd7169f894bfb9296b8f3 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/smolvlm/configuration_smolvlm.py @@ -0,0 +1,194 @@ +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# This file was automatically generated from src/transformers/models/smolvlm/modular_smolvlm.py. +# Do NOT edit this file manually as any edits will be overwritten by the generation of +# the file from the modular. If any change should be done, please apply the change to the +# modular_smolvlm.py file directly. One of our CI enforces this. +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# Copyright 2025 the HuggingFace Inc. team. All rights reserved. +# Written by Orr Zohar +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +from ...configuration_utils import PreTrainedConfig +from ...utils import logging +from ..auto import CONFIG_MAPPING, AutoConfig + + +logger = logging.get_logger(__name__) + + +class SmolVLMVisionConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`SmolVLMVisionModel`]. It is used to instantiate a + SmolVLM vision encoder according to the specified arguments, defining the model architecture. Instantiating a + configuration with the defaults will yield a similar configuration to that of the SigLIP checkpoint + [google/siglip-so400m-patch14-384](https://huggingface.co/google/siglip-so400m-patch14-384) used in SmolVLM + [HuggingFaceTB/SmolVLM2-2.2B-Instruct](https://huggingface.co/HuggingFaceTB/SmolVLM2-2.2B-Instruct). + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + hidden_size (`int`, *optional*, defaults to 1152): + Dimensionality of the encoder layers and the pooler layer. + intermediate_size (`int`, *optional*, defaults to 3072): + Dimensionality of the "intermediate" (i.e., feed-forward) layer in the Transformer encoder. + num_hidden_layers (`int`, *optional*, defaults to 12): + Number of hidden layers in the Transformer encoder. + num_attention_heads (`int`, *optional*, defaults to 16): + Number of attention heads for each attention layer in the Transformer encoder. + num_channels (`int`, *optional*, defaults to 3): + Number of channels in the input images. + image_size (`int`, *optional*, defaults to 224): + The size (resolution) of each image. + patch_size (`int`, *optional*, defaults to 32): + The size (resolution) of each patch. + hidden_act (`str` or `function`, *optional*, defaults to `"gelu_pytorch_tanh"`): + The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`, + `"relu"`, `"selu"` and `"gelu_new"` `"quick_gelu"` are supported. + layer_norm_eps (`float`, *optional*, defaults to 1e-06): + The epsilon used by the layer normalization layers. + attention_dropout (`float`, *optional*, defaults to 0.0): + The dropout ratio for the attention probabilities. + initializer_range (`float`, *optional*, defaults to 0.02): + The standard deviation of the truncated_normal_initializer for initializing all weight matrices. + + Example: + + ```python + >>> from transformers.models.smolvlm.modeling_smolvlm import SmolVLMVisionTransformer + >>> from transformers.models.smolvlm.configuration_smolvlm import SmolVLMVisionConfig + + >>> # Initializing a SmolVLMVisionConfig with google/siglip-so400m-patch14-384 style configuration + >>> configuration = SmolVLMVisionConfig() + + >>> # Initializing a SmolVLMVisionTransformer (with random weights) from the google/siglip-so400m-patch14-384 style configuration + >>> model = SmolVLMVisionTransformer(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "smolvlm_vision" + base_config_key = "vision_config" + + def __init__( + self, + hidden_size=1152, + intermediate_size=3072, + num_hidden_layers=12, + num_attention_heads=16, + num_channels=3, + image_size=224, + patch_size=32, + hidden_act="gelu_pytorch_tanh", + layer_norm_eps=1e-6, + attention_dropout=0.0, + initializer_range=0.02, + **kwargs, + ): + super().__init__(**kwargs) + + self.hidden_size = hidden_size + self.intermediate_size = intermediate_size + self.num_hidden_layers = num_hidden_layers + self.num_attention_heads = num_attention_heads + self.num_channels = num_channels + self.patch_size = patch_size + self.image_size = image_size + self.attention_dropout = attention_dropout + self.layer_norm_eps = layer_norm_eps + self.hidden_act = hidden_act + self.initializer_range = initializer_range + + +class SmolVLMConfig(PreTrainedConfig): + r""" + This is the configuration class to store the configuration of a [`SmolVLMModel`]. It is used to instantiate a + SmolVLM model according to the specified arguments, defining the model architecture. Instantiating a + configuration with the defaults will yield a similar configuration to that of the model of the SmolVLM + [HuggingFaceTB/SmolVLM2-2.2B-Instruct](https://huggingface.co/HuggingFaceTB/SmolVLM2-2.2B-Instruct) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + use_cache (`bool`, *optional*, defaults to `True`): + Whether or not the model should cache the key/value pairs of the attention mechanism. Only + relevant if `config.is_decoder=True`. + image_token_id (`int`, *optional*, defaults to 128257): + The id of the "image" token. + tie_word_embeddings (`bool`, *optional*, defaults to `False`): + Whether or not to tie the word embeddings with the token embeddings. + vision_config (`IdeficsVisionConfig` or `dict`, *optional*, defaults to `IdeficsVisionConfig`): + Custom vision config or dict for the vision tower + text_config (`PreTrainedConfig` or `dict`, *optional*, defaults to `LlamaConfig`): + Custom text config or dict for the text model + scale_factor (`int`, *optional*, defaults to 2): + The scale factor for the image encoder. + pad_token_id (`int`, *optional*, defaults to 128002): + The id of the padding token. + + Example: + ```python + >>> from transformers import SmolVLMModel, SmolVLMConfig + >>> # Initializing configuration + >>> configuration = SmolVLMConfig() + >>> # Initializing a model from the configuration + >>> model = SmolVLMModel(configuration) + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "smolvlm" + sub_configs = {"text_config": AutoConfig, "vision_config": SmolVLMVisionConfig} + + def __init__( + self, + use_cache=True, + image_token_id=128257, + tie_word_embeddings=False, + vision_config=None, + text_config=None, + scale_factor=2, + pad_token_id=128_002, + **kwargs, + ): + self.image_token_id = image_token_id + self.use_cache = use_cache + self.tie_word_embeddings = tie_word_embeddings + + if vision_config is None: + self.vision_config = SmolVLMVisionConfig() + logger.info("vision_config is None, using default vision config") + elif isinstance(vision_config, dict): + self.vision_config = SmolVLMVisionConfig(**vision_config) + elif isinstance(vision_config, SmolVLMVisionConfig): + self.vision_config = vision_config + + if isinstance(text_config, dict): + text_config["model_type"] = text_config.get("model_type", "llama") + text_config = CONFIG_MAPPING[text_config["model_type"]](**text_config) + elif text_config is None: + logger.info("text_config is None, using default text config") + text_config = CONFIG_MAPPING["llama"]( + rms_norm_eps=1e-5, + pad_token_id=pad_token_id, + ) + self.text_config = text_config + self.scale_factor = scale_factor + + super().__init__(**kwargs) + + +__all__ = ["SmolVLMVisionConfig", "SmolVLMConfig"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/smolvlm/image_processing_smolvlm.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/smolvlm/image_processing_smolvlm.py new file mode 100644 index 0000000000000000000000000000000000000000..c86beab858a28fc65811fb5f4e682523f93d9363 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/smolvlm/image_processing_smolvlm.py @@ -0,0 +1,913 @@ +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# This file was automatically generated from src/transformers/models/smolvlm/modular_smolvlm.py. +# Do NOT edit this file manually as any edits will be overwritten by the generation of +# the file from the modular. If any change should be done, please apply the change to the +# modular_smolvlm.py file directly. One of our CI enforces this. +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# Copyright 2025 the HuggingFace Inc. team. All rights reserved. +# Written by Orr Zohar +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import math +from collections.abc import Iterable + +import numpy as np + +from ...image_processing_utils import BaseImageProcessor, BatchFeature +from ...image_transforms import PaddingMode, pad, to_channel_dimension_format, to_pil_image +from ...image_utils import ( + IMAGENET_STANDARD_MEAN, + IMAGENET_STANDARD_STD, + ChannelDimension, + ImageInput, + PILImageResampling, + get_image_size, + infer_channel_dimension_format, + is_scaled_image, + make_nested_list_of_images, + to_numpy_array, + valid_images, + validate_preprocess_arguments, +) +from ...processing_utils import ImagesKwargs +from ...utils import TensorType, is_vision_available, logging + + +if is_vision_available(): + import PIL + from PIL import Image + + +logger = logging.get_logger(__name__) + + +class SmolVLMImageProcessorKwargs(ImagesKwargs, total=False): + """ + do_image_splitting (`bool`, *optional*, defaults to `True`): + Whether to split the image into sub-images concatenated with the original image. They are split into patches + such that each patch has a size of `max_image_size["height"]` x `max_image_size["width"]`. + max_image_size (`Dict`, *optional*, defaults to `{"longest_edge": 364}`): + Maximum resolution of the patches of images accepted by the model. This is a dictionary containing the key "longest_edge". + return_row_col_info (`bool`, *optional*, defaults to `False`): + Whether to return the row and column information of the images. + """ + + do_image_splitting: bool + max_image_size: dict[str, int] + return_row_col_info: bool + + +MAX_IMAGE_SIZE = 4096 # 4k resolution as absolute maximum + + +def _resize_output_size_rescale_to_max_len( + height: int, width: int, min_len: int | None = 1, max_len: int | None = None +) -> tuple[int, int]: + """ + Get the output size of the image after resizing given a dictionary specifying the max and min sizes. + Args: + height (`int`): + Height of the input image. + width (`int`): + Width of the input image. + min_len (`int`, *optional*, defaults to 1): + Minimum size of the output image. + max_len (`int`, *optional*, defaults to the maximum size of the image): + Maximum size of the output image. + Returns: + The output size of the image after resizing. + """ + max_len = max(height, width) if max_len is None else max_len + aspect_ratio = width / height + + if width >= height: + width = max_len + height = int(width / aspect_ratio) + if height % 2 != 0: + height += 1 + elif height > width: + height = max_len + width = int(height * aspect_ratio) + if width % 2 != 0: + width += 1 + + # Avoid resizing to a size smaller than min_len + height = max(height, min_len) + width = max(width, min_len) + return height, width + + +def _resize_output_size_scale_below_upper_bound( + height: int, width: int, max_len: dict[str, int] | None = None +) -> tuple[int, int]: + """ + Get the output size of the image after resizing given a dictionary specifying the max and min sizes. + Args: + height (`int`): + Height of the input image. + width (`int`): + Width of the input image. + max_len (`dict[str, int]`, *optional*, defaults to the maximum size of the image): + Defines the maximum dimensions of the image. + Returns: + The output size of the image after resizing. + """ + max_len = max(height, width) if max_len is None else max_len + + aspect_ratio = width / height + if width >= height and width > max_len: + width = max_len + height = int(width / aspect_ratio) + elif height > width and height > max_len: + height = max_len + width = int(height * aspect_ratio) + + # Avoid resizing to a size smaller than 1 + height = max(height, 1) + width = max(width, 1) + return height, width + + +def get_resize_output_image_size( + image, + resolution_max_side: int, + input_data_format: str | ChannelDimension | None = None, +) -> tuple[int, int]: + """ + Get the output size of the image after resizing given a dictionary specifying the max and min sizes. + Args: + image (`np.ndarray`): + Image to resize. + resolution_max_side (`int`): + The longest edge of the image will be resized to this value. The shortest edge will be resized to keep the + input aspect ratio. + input_data_format (`ChannelDimension` or `str`): + The channel dimension format of the input image. + Returns: + The output size of the image after resizing. + """ + height, width = get_image_size(image, channel_dim=input_data_format) + + # Find the output size, when rescaling the longest edge to max_len and preserving the aspect ratio + height, width = _resize_output_size_rescale_to_max_len(height, width, max_len=resolution_max_side) + # Find the output size when scaling the image to be below the MAX_IMAGE_SIZE + height, width = _resize_output_size_scale_below_upper_bound(height, width, max_len=MAX_IMAGE_SIZE) + return height, width + + +def get_max_height_width( + images_list: list[list[np.ndarray]], input_data_format: str | ChannelDimension | None = None +) -> list[int]: + """ + Get the maximum height and width across all images in a batch. + """ + if input_data_format is None: + input_data_format = infer_channel_dimension_format(images_list[0][0], num_channels=(1, 3, 4)) + + max_height = max_width = float("-inf") + for images in images_list: + for image in images: + height, width = get_image_size(image, channel_dim=input_data_format) + max_height = max(height, max_height) + max_width = max(width, max_width) + return (max_height, max_width) + + +def make_pixel_mask( + image: np.ndarray, output_size: tuple[int, int], input_data_format: str | ChannelDimension | None = None +) -> np.ndarray: + """ + Make a pixel mask for the image, where 1 indicates a valid pixel and 0 indicates padding. + Args: + image (`np.ndarray`): + Image to make the pixel mask for. + output_size (`tuple[int, int]`): + Output size of the mask. + """ + input_height, input_width = get_image_size(image, channel_dim=input_data_format) + mask = np.zeros(output_size, dtype=np.int64) + mask[:input_height, :input_width] = 1 + return mask + + +def convert_to_rgb( + image: np.ndarray, + palette: PIL.ImagePalette.ImagePalette | None = None, + data_format: str | ChannelDimension | None = None, + input_data_format: str | ChannelDimension | None = None, +) -> ImageInput: + """ + Converts an image to RGB format. + Args: + image (`np.ndarray`): + The image to convert. + palette (list[int], *optional*): + The palette to use if given. + data_format (ChannelDimension or str, *optional*): + The channel dimension format for the output image. If not provided, it will be the same as the input image. + input_data_format (ChannelDimension or str, *optional*): + The channel dimension format of the input image. + """ + if input_data_format is None: + input_data_format = infer_channel_dimension_format(image, num_channels=(1, 3, 4)) + + # For all transformations, we want to keep the same data format as the input image unless otherwise specified. + # The resized image from PIL will always have channels last, so find the input format first. + data_format = input_data_format if data_format is None else data_format + + mode = "P" if palette is not None else None + image = to_pil_image(image, image_mode=mode, input_data_format=input_data_format) + if image.mode == "P" and palette is not None: + image.putpalette(palette) + + image_rgba = image.convert("RGBA") + background = Image.new("RGBA", image_rgba.size, (255, 255, 255)) + alpha_composite = Image.alpha_composite(background, image_rgba) + alpha_composite = alpha_composite.convert("RGB") + + output_array = np.array(alpha_composite) + # The image is always in channels last format after converting from a PIL image + output_array = to_channel_dimension_format(output_array, data_format, input_channel_dim=ChannelDimension.LAST) + return output_array + + +# FIXME Amy: make a more general crop function that isn't just centre crop +def _crop( + image: np.ndarray, + w1: int, + h1: int, + w2: int, + h2: int, + data_format: str | ChannelDimension | None = None, +) -> np.ndarray: + if data_format is None: + data_format = infer_channel_dimension_format(image, num_channels=(1, 3, 4)) + + if data_format == ChannelDimension.FIRST: + image = image[:, h1:h2, w1:w2] + elif data_format == ChannelDimension.LAST: + image = image[h1:h2, w1:w2, :] + else: + raise ValueError("Invalid channel dimension format.") + + return image + + +class SmolVLMImageProcessor(BaseImageProcessor): + r""" + Constructs a SmolVLM image processor. + Args: + do_convert_rgb (`bool`, *optional*, defaults to `True`): + Whether to convert the image to RGB. This is useful if the input image is of a different format e.g. RGBA. + Only has an effect if the input image is in the PIL format. + do_resize (`bool`, *optional*, defaults to `True`): + Whether to resize the image. The longest edge of the image is resized to be <= `size["longest_edge"]`, with the + shortest edge resized to keep the input aspect ratio. + size (`Dict`, *optional*, defaults to `{"longest_edge": 4 * 364}`): + Controls the size of the output image. This is a dictionary containing the key "longest_edge". + The image will be resized such that the longest edge is <= `size["longest_edge"]` and the shortest edge is resized + to keep the input aspect ratio. + resample (`Resampling`, *optional*, defaults to `Resampling.LANCZOS`): + Resampling filter to use when resizing the image. + do_image_splitting (`bool`, *optional*, defaults to `True`): + Whether to split the image into sub-images concatenated with the original image. They are split into patches + such that each patch has a size of `max_image_size["height"]` x `max_image_size["width"]`. + max_image_size (`Dict`, *optional*, defaults to `{"longest_edge": 364}`): + Maximum resolution of the patches of images accepted by the model. This is a dictionary containing the key "longest_edge". + do_rescale (`bool`, *optional*, defaults to `True`): + Whether to rescale the image. If set to `True`, the image is rescaled to have pixel values between 0 and 1. + rescale_factor (`float`, *optional*, defaults to `1/255`): + Rescale factor to rescale the image by if `do_rescale` is set to `True`. + do_normalize (`bool`, *optional*, defaults to `True`): + Whether to normalize the image. If set to `True`, the image is normalized to have a mean of `image_mean` and + a standard deviation of `image_std`. + image_mean (`float` or `list[float]`, *optional*, defaults to `IDEFICS_STANDARD_MEAN`): + Mean to use if normalizing the image. This is a float or list of floats the length of the number of + channels in the image. Can be overridden by the `image_mean` parameter in the `preprocess` method. Can be + overridden by the `image_mean` parameter in the `preprocess` method. + image_std (`float` or `list[float]`, *optional*, defaults to `IDEFICS_STANDARD_STD`): + Standard deviation to use if normalizing the image. This is a float or list of floats the length of the + number of channels in the image. Can be overridden by the `image_std` parameter in the `preprocess` method. + Can be overridden by the `image_std` parameter in the `preprocess` method. + do_pad (`bool`, *optional*, defaults to `True`): + Whether or not to pad the images to the largest height and width in the batch and number of images per + sample in the batch, such that the returned tensor is of shape (batch_size, max_num_images, num_channels, max_height, max_width). + """ + + model_input_names = ["pixel_values", "pixel_attention_mask"] + valid_kwargs = SmolVLMImageProcessorKwargs + + def __init__( + self, + do_convert_rgb: bool = True, + do_resize: bool = True, + size: dict[str, int] | None = None, + resample: PILImageResampling = PILImageResampling.LANCZOS, + do_image_splitting: bool = True, + max_image_size: dict[str, int] | None = None, + do_rescale: bool = True, + rescale_factor: float = 1 / 255, + do_normalize: bool = True, + image_mean: float | list[float] | None = None, + image_std: float | list[float] | None = None, + do_pad: bool = True, + **kwargs, + ) -> None: + super().__init__(**kwargs) + self.do_convert_rgb = do_convert_rgb + self.do_resize = do_resize + self.size = size if size is not None else {"longest_edge": 4 * 364} + self.resample = resample + self.do_image_splitting = do_image_splitting + self.max_image_size = max_image_size if max_image_size is not None else {"longest_edge": 364} + self.do_rescale = do_rescale + self.rescale_factor = rescale_factor + self.do_normalize = do_normalize + self.image_mean = image_mean if image_mean is not None else IMAGENET_STANDARD_MEAN + self.image_std = image_std if image_std is not None else IMAGENET_STANDARD_STD + self.do_pad = do_pad + + def resize( + self, + image: np.ndarray, + size: dict[str, int], + resample: PILImageResampling = PILImageResampling.LANCZOS, + data_format: str | ChannelDimension | None = None, + input_data_format: str | ChannelDimension | None = None, + **kwargs, + ) -> np.ndarray: + """ + Resize an image. The longest edge of the image is resized to size["longest_edge"], with the shortest edge + resized to keep the input aspect ratio. Can also be used with size["height"] and size["width"]. + Args: + image (`np.ndarray`): + Image to resize. + size (`dict[str, int]`): + Size of the output image. + resample (`PILImageResampling`, *optional*, defaults to `PILImageResampling.LANCZOS`): + Resampling filter to use when resizing the image. + data_format (`ChannelDimension` or `str`, *optional*): + The channel dimension format of the output image. If not provided, it will be the same as the input image. + input_data_format (`ChannelDimension` or `str`, *optional*): + The channel dimension format of the input image. If not provided, it will be inferred. + """ + if input_data_format is None: + input_data_format = infer_channel_dimension_format(image, num_channels=(1, 3, 4)) + + # For all transformations, we want to keep the same data format as the input image unless otherwise specified. + # The resized image from PIL will always have channels last, so find the input format first. + data_format = input_data_format if data_format is None else data_format + + if "longest_edge" in size: + size = get_resize_output_image_size( + image, resolution_max_side=size["longest_edge"], input_data_format=input_data_format + ) + elif "height" in size and "width" in size: + size = (size["height"], size["width"]) + else: + raise ValueError("size must be a dictionary with key 'longest_edge' or 'height' and 'width'.") + + image_mode = None + if image.ndim == 2 or image.shape[-1] == 1: + image_mode = "P" + image = to_pil_image(image, image_mode=image_mode, input_data_format=input_data_format) + + resized_image = image.resize((size[1], size[0]), resample=resample) + resized_image = np.array(resized_image) + + # If the input image channel dimension was of size 1, then it is dropped when converting to a PIL image + # so we need to add it back if necessary. + resized_image = np.expand_dims(resized_image, axis=-1) if resized_image.ndim == 2 else resized_image + # The image is always in channels last format after converting from a PIL image + resized_image = to_channel_dimension_format( + resized_image, data_format, input_channel_dim=ChannelDimension.LAST + ) + return resized_image + + def split_image( + self, + image, + max_image_size: dict[str, int], + resample: PILImageResampling = PILImageResampling.LANCZOS, + data_format: str | ChannelDimension | None = None, + input_data_format: str | ChannelDimension | None = None, + ): + """ + Split an image into squares of side max_image_size and the original image resized to max_image_size. + That means that a single image becomes a sequence of images. + This is a "trick" to spend more compute on each image with no changes in the vision encoder. + 1) If one side of the original image is larger than `max_image_size`, resize it to `max_image_size` while preserving the aspect ratio. + 2) Divide the resulting image into `ceil(height / max_image_size)` x `ceil(width / max_image_size)` + sub-images of the same size each (image_size, image_size). Typically, 364x364. + 3) Returns the list of the crops and the original image, in addition to the number of splits for the height and the width. + Args: + image (`np.ndarray`): + Images to split. + max_image_size (`dict[str, int]`): + Maximum size of the output image. If the image is larger than this size, it will be split into + patches of this size, and the original image will be concatenated with the patches, resized to max_size. + resample (`PILImageResampling`, *optional*, defaults to `PILImageResampling.LANCZOS`): + Resampling filter to use when resizing the image. + data_format (`ChannelDimension` or `str`, *optional*): + The channel dimension format of the output image. If not provided, it will be the same as the input image. + input_data_format (`ChannelDimension` or `str`, *optional*): + The channel dimension format of the input image. If not provided, it will be inferred. + """ + height, width = get_image_size(image, channel_dim=input_data_format) + max_height = max_width = max_image_size["longest_edge"] + + frames = [] + if height > max_height or width > max_width: + # Calculate the number of splits + num_splits_h = math.ceil(height / max_height) + num_splits_w = math.ceil(width / max_width) + # Calculate the optimal width and height for the sub-images + optimal_height = math.ceil(height / num_splits_h) + optimal_width = math.ceil(width / num_splits_w) + + # Iterate through each row and column + for r in range(num_splits_h): + for c in range(num_splits_w): + # Calculate the starting point of the crop + start_x = c * optimal_width + start_y = r * optimal_height + + # Calculate the ending point of the crop + end_x = min(start_x + optimal_width, width) + end_y = min(start_y + optimal_height, height) + + # Crop the image + cropped_image = _crop( + image, + start_x, + start_y, + end_x, + end_y, + data_format=data_format, + ) + frames.append(cropped_image) + + # For the global image at the end, we resize it to match the max_image_size, for cpu memory efficiency + global_image_height, global_image_width = max_height, max_width + if height != global_image_height or width != global_image_width: + image = self.resize( + image, + {"height": global_image_height, "width": global_image_width}, + resample=resample, + input_data_format=data_format, + ) + else: + num_splits_h, num_splits_w = 0, 0 + + frames.append(image) + + return frames, num_splits_h, num_splits_w + + def resize_for_vision_encoder( + self, + image: np.ndarray, + vision_encoder_max_size: int, + resample: PILImageResampling = PILImageResampling.LANCZOS, + data_format: str | ChannelDimension | None = None, + input_data_format: str | ChannelDimension | None = None, + ): + """ + Resize images to be multiples of `vision_encoder_max_size` while preserving the aspect ratio. + Args: + image (`np.ndarray`): + Images to resize. + vision_encoder_max_size (`int`): + Maximum size of the output image. If the image is larger than this size, it will be split into + patches of this size, and the original image will be concatenated with the patches, resized to max_size. + resample (`PILImageResampling`, *optional*, defaults to `PILImageResampling.LANCZOS`): + Resampling filter to use when resizing the image. + data_format (`ChannelDimension` or `str`, *optional*): + The channel dimension format of the output image. If not provided, it will be the same as the input image. + input_data_format (`ChannelDimension` or `str`, *optional*): + The channel dimension format of the input image. If not provided, it will be inferred + """ + height, width = get_image_size(image, channel_dim=input_data_format) + + aspect_ratio = width / height + if width >= height: + width = math.ceil(width / vision_encoder_max_size) * vision_encoder_max_size + height = int(width / aspect_ratio) + height = math.ceil(height / vision_encoder_max_size) * vision_encoder_max_size + elif height > width: + height = math.ceil(height / vision_encoder_max_size) * vision_encoder_max_size + width = int(height * aspect_ratio) + width = math.ceil(width / vision_encoder_max_size) * vision_encoder_max_size + new_size = {"height": height, "width": width} + return self.resize( + image, size=new_size, resample=resample, input_data_format=input_data_format, data_format=data_format + ) + + def _pad_image( + self, + image: np.ndarray, + output_size: tuple[int, int], + constant_values: float | Iterable[float] = 0, + data_format: ChannelDimension | None = None, + input_data_format: str | ChannelDimension | None = None, + ) -> np.ndarray: + """ + Pad an image with zeros to the given size. + """ + input_height, input_width = get_image_size(image, channel_dim=input_data_format) + output_height, output_width = output_size + + pad_bottom = output_height - input_height + pad_right = output_width - input_width + padding = ((0, pad_bottom), (0, pad_right)) + padded_image = pad( + image, + padding, + mode=PaddingMode.CONSTANT, + constant_values=constant_values, + data_format=data_format, + input_data_format=input_data_format, + ) + return padded_image + + def pad( + self, + images: list[list[np.ndarray]], + constant_values: float | Iterable[float] = 0, + return_pixel_mask: bool = True, + return_tensors: str | TensorType | None = None, + data_format: ChannelDimension | None = None, + input_data_format: str | ChannelDimension | None = None, + ) -> BatchFeature: + """ + For a list of images, for each images, pads a batch of images to the bottom and right of the image with zeros to the size of largest height and width. + For each sample in the batch, pads the sample with empty images to the max_number of images per sample in the batch. Optionally returns a pixel mask. + Args: + images (`list[list[np.ndarray]]`): + List of list of images to pad. Pads to the largest height and width in the batch. + constant_values (`float` or `Iterable[float]`, *optional*): + The value to use for the padding if `mode` is `"constant"`. + return_pixel_mask (`bool`, *optional*, defaults to `True`): + Whether to return a pixel mask. + return_tensors (`str` or `TensorType`, *optional*): + The type of tensors to return. Can be one of: + - Unset: Return a list of `np.ndarray`. + - `TensorType.PYTORCH` or `'pt'`: Return a batch of type `torch.Tensor`. + - `TensorType.NUMPY` or `'np'`: Return a batch of type `np.ndarray`. + data_format (`str` or `ChannelDimension`, *optional*): + The channel dimension format of the image. If not provided, it will be the same as the input image. + input_data_format (`ChannelDimension` or `str`, *optional*): + The channel dimension format of the input image. If not provided, it will be inferred. + """ + pad_size = get_max_height_width(images, input_data_format=input_data_format) + + batch_size = len(images) + max_num_images = max(len(images_) for images_ in images) + input_data_format = ( + infer_channel_dimension_format(images[0][0], num_channels=(1, 3, 4)) + if input_data_format is None + else input_data_format + ) + data_format = input_data_format if data_format is None else data_format + # filter out empty image lists, then take first image of the first sample + first_image_in_list = [sample_images for sample_images in images if sample_images][0][0] + + if input_data_format == ChannelDimension.FIRST: + n_channels = first_image_in_list.shape[0] + elif input_data_format == ChannelDimension.LAST: + n_channels = first_image_in_list.shape[-1] + else: + raise ValueError("Invalid channel dimension format.") + + def empty_image(size, input_data_format): + if input_data_format == ChannelDimension.FIRST: + return np.zeros((n_channels, *size), dtype=np.uint8) + elif input_data_format == ChannelDimension.LAST: + return np.zeros((*size, n_channels), dtype=np.uint8) + + padded_images_list = [ + [empty_image(pad_size, data_format) for _ in range(max_num_images)] for _ in range(batch_size) + ] + padded_masks = [[np.zeros(pad_size, dtype=np.int64) for _ in range(max_num_images)] for _ in range(batch_size)] + + for batch_idx in range(batch_size): + for sample_idx, image in enumerate(images[batch_idx]): + padded_images_list[batch_idx][sample_idx] = self._pad_image( + image, + pad_size, + constant_values=constant_values, + data_format=data_format, + input_data_format=input_data_format, + ) + padded_masks[batch_idx][sample_idx] = make_pixel_mask( + image, output_size=pad_size, input_data_format=input_data_format + ) + + padded_masks = padded_masks if return_pixel_mask else None + return padded_images_list, padded_masks + + def preprocess( + self, + images: ImageInput, + do_convert_rgb: bool | None = None, + do_resize: bool | None = None, + size: dict[str, int] | None = None, + resample: PILImageResampling | None = None, + do_image_splitting: bool | None = None, + do_rescale: bool | None = None, + max_image_size: dict[str, int] | None = None, + rescale_factor: float | None = None, + do_normalize: bool | None = None, + image_mean: float | list[float] | None = None, + image_std: float | list[float] | None = None, + do_pad: bool | None = None, + return_tensors: str | TensorType | None = None, + return_row_col_info: bool = False, + data_format: ChannelDimension | None = ChannelDimension.FIRST, + input_data_format: str | ChannelDimension | None = None, + ): + """ + Preprocess a batch of images. + Args: + images (`ImageInput`): + A list of images to preprocess. + do_convert_rgb (`bool`, *optional*, defaults to `self.do_convert_rgb`): + Whether to convert the image to RGB. + do_resize (`bool`, *optional*, defaults to `self.do_resize`): + Whether to resize the image. + size (`dict[str, int]`, *optional*, defaults to `self.size`): + Size of the image after resizing. With the longest edge resized to keep the input aspect ratio. + resample (`int`, *optional*, defaults to `self.resample`): + Resampling filter to use if resizing the image. This can be one of the enum `PILImageResampling`. Only + has an effect if `do_resize` is set to `True`. + do_image_splitting (`bool`, *optional*, defaults to `self.do_image_splitting`): + Whether to split the image into sub-images concatenated with the original image. They are split into patches + such that each patch has a size of `max_image_size["height"]` x `max_image_size["width"]`. + max_image_size (`Dict`, *optional*, defaults to `self.max_image_size`): + Maximum resolution of the images. If the image is larger than this size, the image is split into patches. + do_rescale (`bool`, *optional*, defaults to `self.do_rescale`): + Whether to rescale the image. + rescale_factor (`float`, *optional*, defaults to `self.rescale_factor`): + Rescale factor to rescale the image by if `do_rescale` is set to `True`. + do_normalize (`bool`, *optional*, defaults to `self.do_normalize`): + Whether to normalize the image. + image_mean (`float` or `list[float]`, *optional*, defaults to `self.image_mean`): + Image mean to use for normalization. Only has an effect if `do_normalize` is set to `True`. + image_std (`float` or `list[float]`, *optional*, defaults to `self.image_std`): + Image standard deviation to use for normalization. Only has an effect if `do_normalize` is set to + `True`. + do_pad (`bool`, *optional*, defaults to `self.do_pad`): + Whether or not to pad the images to the largest height and width in the batch. + return_tensors (`str` or `TensorType`, *optional*): + The type of tensors to return. Can be one of: + - Unset: Return a list of `np.ndarray`. + - `TensorType.PYTORCH` or `'pt'`: Return a batch of type `torch.Tensor`. + - `TensorType.NUMPY` or `'np'`: Return a batch of type `np.ndarray`. + return_row_col_info (`bool`, *optional*, default to `False`): + Whether to return the number of rows and columns of the split images. This is used for the + `SmolVLMProcessor` to generate prompt strings based on the number of rows and columns. + data_format (`ChannelDimension` or `str`, *optional*, defaults to `ChannelDimension.FIRST`): + The channel dimension format for the output image. Can be one of: + - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format. + - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format. + - Unset: Use the channel dimension format of the input image. + input_data_format (`ChannelDimension` or `str`, *optional*): + The channel dimension format for the input image. If unset, the channel dimension format is inferred + from the input image. Can be one of: + - `"channels_first"` or `ChannelDimension.FIRST`: image in (num_channels, height, width) format. + - `"channels_last"` or `ChannelDimension.LAST`: image in (height, width, num_channels) format. + - `"none"` or `ChannelDimension.NONE`: image in (height, width) format. + """ + do_resize = do_resize if do_resize is not None else self.do_resize + size = size if size is not None else self.size + resample = resample if resample is not None else self.resample + do_rescale = do_rescale if do_rescale is not None else self.do_rescale + rescale_factor = rescale_factor if rescale_factor is not None else self.rescale_factor + do_image_splitting = do_image_splitting if do_image_splitting is not None else self.do_image_splitting + max_image_size = max_image_size if max_image_size is not None else self.max_image_size + do_normalize = do_normalize if do_normalize is not None else self.do_normalize + image_mean = image_mean if image_mean is not None else self.image_mean + image_std = image_std if image_std is not None else self.image_std + do_convert_rgb = do_convert_rgb if do_convert_rgb is not None else self.do_convert_rgb + do_pad = do_pad if do_pad is not None else self.do_pad + + images = self.fetch_images(images) + images_list = make_nested_list_of_images(images) + + if not valid_images(images_list[0]): + raise ValueError("Invalid image type. Must be of type PIL.Image.Image, numpy.ndarray, or torch.Tensor") + + validate_preprocess_arguments( + do_rescale=do_rescale, + rescale_factor=rescale_factor, + do_normalize=do_normalize, + image_mean=image_mean, + image_std=image_std, + do_resize=do_resize, + size=size, + resample=resample, + ) + + # save the palettes for conversion to RGB + palettes_list = [ + [im.getpalette() if isinstance(im, Image.Image) and im.mode == "P" else None for im in images] + for images in images_list + ] + + # All transformations expect numpy arrays. + images_list = [[to_numpy_array(image) for image in images] for images in images_list] + # Search for the first image in the image list. + # NOTE: we can't slice the first image with images_list[0][0] if the first batch contains no images. See #36682 + first_image_in_list = [images for images in images_list if images][0][0] + + # Extra channel dimension for grayscale images + if input_data_format in [ChannelDimension.LAST, None]: + images_list = [ + [np.expand_dims(img, axis=-1) if img.ndim == 2 else img for img in images] for images in images_list + ] + elif input_data_format == ChannelDimension.FIRST: + images_list = [ + [np.expand_dims(img, axis=0) if img.ndim == 2 else img for img in images] for images in images_list + ] + + if do_rescale and is_scaled_image(first_image_in_list): + logger.warning_once( + "It looks like you are trying to rescale already rescaled images. If the input" + " images have pixel values between 0 and 1, set `do_rescale=False` to avoid rescaling them again." + ) + + # We assume that all images have the same channel dimension format. + if input_data_format is None: + input_data_format = infer_channel_dimension_format(first_image_in_list, num_channels=(1, 3, 4)) + + if do_resize: + images_list = [ + [ + self.resize(image=image, size=size, resample=resample, input_data_format=input_data_format) + for image in images + ] + for images in images_list + ] + + if do_image_splitting: + # We first resize both height and width of each image to the nearest max_image_size multiple, disregarding the aspect ratio + # for size=(10, max_image_size) -> rescaled_size=(max_image_size, max_image_size) + # for size=(11, max_image_size+1) -> rescaled_size=(max_image_size, max_image_size*2) + images_list = [ + [ + self.resize_for_vision_encoder( + image, max_image_size["longest_edge"], resample=resample, input_data_format=input_data_format + ) + for image in images + ] + for images in images_list + ] + images_list_split_arrays = [] + palettes_list_split_arrays = [] + images_list_rows = [] + images_list_cols = [] + for images, palettes in zip(images_list, palettes_list): + split_image_arrays = [] + split_palettes_arrays = [] + image_rows = [] + image_cols = [] + for image, palette in zip(images, palettes): + split_image_array, rows, cols = self.split_image( + image, + max_image_size=max_image_size, + resample=resample, + input_data_format=input_data_format, + ) + split_image_arrays.extend(split_image_array) + split_palettes_arrays.extend([palette] * len(split_image_array)) + image_rows.append(rows) + image_cols.append(cols) + images_list_split_arrays.append(split_image_arrays) + palettes_list_split_arrays.append(split_palettes_arrays) + images_list_rows.append(image_rows) + images_list_cols.append(image_cols) + images_list = images_list_split_arrays + palettes_list = palettes_list_split_arrays + else: + # We square the images to max_image_size + images_list = [ + [ + self.resize( + image=image, + size={"height": max_image_size["longest_edge"], "width": max_image_size["longest_edge"]}, + resample=resample, + input_data_format=input_data_format, + ) + for image in images + ] + for images in images_list + ] + images_list_rows = [[0] * len(images) for images in images_list] + images_list_cols = [[0] * len(images) for images in images_list] + + if do_convert_rgb: + images_list = [ + [convert_to_rgb(img, palette) for img, palette in zip(images, palettes)] + for images, palettes in zip(images_list, palettes_list) + ] + + if do_rescale: + images_list = [ + [self.rescale(image, rescale_factor, input_data_format=input_data_format) for image in images] + for images in images_list + ] + + if do_normalize: + images_list = [ + [ + self.normalize(image=image, mean=image_mean, std=image_std, input_data_format=input_data_format) + for image in images + ] + for images in images_list + ] + + pixel_attention_mask = None + if do_pad: + images_list, pixel_attention_mask = self.pad( + images_list, return_pixel_mask=True, return_tensors=return_tensors, input_data_format=input_data_format + ) + + if data_format is not None: + images_list = [ + [ + to_channel_dimension_format(image, data_format, input_channel_dim=input_data_format) + for image in images + ] + for images in images_list + ] + + # Faster tensor conversion + data = {"pixel_values": np.array(images_list) if do_pad and return_tensors is not None else images_list} + if pixel_attention_mask is not None: + data["pixel_attention_mask"] = ( + np.array(pixel_attention_mask) if do_pad and return_tensors is not None else pixel_attention_mask + ) + + encoding = BatchFeature(data=data, tensor_type=return_tensors) + + # This is needed for generating correct text inputs in the processor - we don't pad to the max number of images + if return_row_col_info: + encoding["rows"] = images_list_rows + encoding["cols"] = images_list_cols + + return encoding + + def get_number_of_image_patches(self, height: int, width: int, images_kwargs: dict): + """ + A utility that returns number of image patches for a given image size. + + Args: + height (`int`): + Height of the input image. + width (`int`): + Width of the input image. + images_kwargs (`dict`) + Any kwargs to override defaults of the image processor. + Returns: + `int`: Number of patches per image. + """ + do_image_splitting = images_kwargs.get("do_image_splitting", self.do_image_splitting) + max_image_size = images_kwargs.get("max_image_size", self.max_image_size) + size = images_kwargs.get("size", self.size) + + num_patches = num_rows = num_cols = 0 + if do_image_splitting: + height, width = _resize_output_size_rescale_to_max_len(height, width, max_len=size["longest_edge"]) + height, width = _resize_output_size_scale_below_upper_bound(height, width, max_len=4096) + aspect_ratio = width / height + + if width >= height: + resized_width = math.ceil(width / max_image_size["longest_edge"]) * max_image_size["longest_edge"] + resized_height = int(width / aspect_ratio) + resized_height = math.ceil(height / max_image_size["longest_edge"]) * max_image_size["longest_edge"] + elif height > width: + resized_height = math.ceil(height / max_image_size["longest_edge"]) * max_image_size["longest_edge"] + resized_width = int(height * aspect_ratio) + resized_width = math.ceil(width / max_image_size["longest_edge"]) * max_image_size["longest_edge"] + + max_height = max_width = max_image_size["longest_edge"] + if resized_height > max_height or resized_width > max_width: + # Calculate the number of splits + num_rows = math.ceil(resized_height / max_height) + num_cols = math.ceil(resized_width / max_width) + num_patches = num_rows * num_cols + 1 + + return num_patches, num_rows, num_cols + + +__all__ = ["SmolVLMImageProcessor"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/smolvlm/image_processing_smolvlm_fast.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/smolvlm/image_processing_smolvlm_fast.py new file mode 100644 index 0000000000000000000000000000000000000000..59ba2fc1f1548c7fb8f475c7980d70eb72190ba8 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/smolvlm/image_processing_smolvlm_fast.py @@ -0,0 +1,536 @@ +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# This file was automatically generated from src/transformers/models/smolvlm/modular_smolvlm.py. +# Do NOT edit this file manually as any edits will be overwritten by the generation of +# the file from the modular. If any change should be done, please apply the change to the +# modular_smolvlm.py file directly. One of our CI enforces this. +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# Copyright 2025 the HuggingFace Inc. team. All rights reserved. +# Written by Orr Zohar +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import math +from typing import Optional + +import torch + +from ...image_processing_utils import BatchFeature +from ...image_processing_utils_fast import BaseImageProcessorFast, SizeDict, group_images_by_shape, reorder_images +from ...image_utils import ( + IMAGENET_STANDARD_MEAN, + IMAGENET_STANDARD_STD, + ImageInput, + PILImageResampling, + make_nested_list_of_images, +) +from ...processing_utils import Unpack +from ...utils import TensorType, auto_docstring, is_torchvision_available, logging +from .image_processing_smolvlm import SmolVLMImageProcessorKwargs + + +if is_torchvision_available(): + from torchvision.transforms import functional as F + + +logger = logging.get_logger(__name__) + +MAX_IMAGE_SIZE = 4096 # 4k resolution as absolute maximum + + +def _resize_output_size_rescale_to_max_len( + height: int, width: int, min_len: int | None = 1, max_len: int | None = None +) -> tuple[int, int]: + """ + Get the output size of the image after resizing given a dictionary specifying the max and min sizes. + Args: + height (`int`): + Height of the input image. + width (`int`): + Width of the input image. + min_len (`int`, *optional*, defaults to 1): + Minimum size of the output image. + max_len (`int`, *optional*, defaults to the maximum size of the image): + Maximum size of the output image. + Returns: + The output size of the image after resizing. + """ + max_len = max(height, width) if max_len is None else max_len + aspect_ratio = width / height + + if width >= height: + width = max_len + height = int(width / aspect_ratio) + if height % 2 != 0: + height += 1 + elif height > width: + height = max_len + width = int(height * aspect_ratio) + if width % 2 != 0: + width += 1 + + # Avoid resizing to a size smaller than min_len + height = max(height, min_len) + width = max(width, min_len) + return height, width + + +def _resize_output_size_scale_below_upper_bound( + height: int, width: int, max_len: dict[str, int] | None = None +) -> tuple[int, int]: + """ + Get the output size of the image after resizing given a dictionary specifying the max and min sizes. + Args: + height (`int`): + Height of the input image. + width (`int`): + Width of the input image. + max_len (`Dict[str, int]`, *optional*, defaults to the maximum size of the image): + Defines the maximum dimensions of the image. + Returns: + The output size of the image after resizing. + """ + max_len = max(height, width) if max_len is None else max_len + + aspect_ratio = width / height + if width >= height and width > max_len: + width = max_len + height = int(width / aspect_ratio) + elif height > width and height > max_len: + height = max_len + width = int(height * aspect_ratio) + + # Avoid resizing to a size smaller than 1 + height = max(height, 1) + width = max(width, 1) + return height, width + + +def get_resize_output_image_size( + image, + resolution_max_side: int, +) -> tuple[int, int]: + """ + Get the output size of the image after resizing given a dictionary specifying the max and min sizes. + Args: + image (`torch.Tensor`): + Image to resize. + resolution_max_side (`int`): + The longest edge of the image will be resized to this value. The shortest edge will be resized to keep the + input aspect ratio. + Returns: + The output size of the image after resizing. + """ + height, width = image.size()[-2:] + + # Find the output size, when rescaling the longest edge to max_len and preserving the aspect ratio + height, width = _resize_output_size_rescale_to_max_len(height, width, max_len=resolution_max_side) + # Find the output size when scaling the image to be below the MAX_IMAGE_SIZE + height, width = _resize_output_size_scale_below_upper_bound(height, width, max_len=MAX_IMAGE_SIZE) + return height, width + + +def get_max_height_width(images_list: list[list["torch.Tensor"]]) -> tuple[int, int]: + """ + Get the maximum height and width across all images in a batch. + """ + image_sizes = [] + for images in images_list: + for image in images: + image_sizes.append(image.size()[-2:]) + + max_height = max(size[0] for size in image_sizes) + max_width = max(size[1] for size in image_sizes) + return (max_height, max_width) + + +def get_num_channels(images_list: list[list["torch.Tensor"]]) -> int: + """ + Get the number of channels across all images in a batch. Handle empty sublists like in [[], [image]]. + """ + for images in images_list: + if images: + return images[0].shape[0] + + raise ValueError("No images found in the batch.") + + +def get_device_from_images(images_list: list[list["torch.Tensor"]]) -> "torch.device": + """ + Get the device from the first non-empty element in a nested list of images. + Handle empty sublists like in [[], [image]]. + """ + for images in images_list: + if images: + return images[0].device + + +@auto_docstring +class SmolVLMImageProcessorFast(BaseImageProcessorFast): + resample = PILImageResampling.LANCZOS + image_mean = IMAGENET_STANDARD_MEAN + image_std = IMAGENET_STANDARD_STD + size = {"longest_edge": 4 * 364} + max_image_size = {"longest_edge": 364} + do_resize = True + do_rescale = True + do_normalize = True + do_convert_rgb = True + do_image_splitting = True + do_pad = True + return_row_col_info = False + valid_kwargs = SmolVLMImageProcessorKwargs + model_input_names = ["pixel_values", "pixel_attention_mask"] + + def _prepare_images_structure(self, images: ImageInput, expected_ndims: int = 3) -> ImageInput: + """ + Prepare a nested images structure for processing. + """ + # Checks for `str` in case of URL/local path and optionally loads images + images = self.fetch_images(images) + return make_nested_list_of_images(images, expected_ndims=expected_ndims) + + def resize( + self, + image: "torch.Tensor", + size: SizeDict, + interpolation: Optional["F.InterpolationMode"] = None, + antialias: bool = True, + **kwargs, + ) -> "torch.Tensor": + """ + Resize an image. The longest edge of the image is resized to size.longest_edge, with the shortest edge + resized to keep the input aspect ratio. Can also be used with size.height and size.width. + Args: + image (`np.ndarray`): + Image to resize. + size (`Dict[str, int]`): + Size of the output image. + interpolation (`InterpolationMode`, *optional*, defaults to `InterpolationMode.BILINEAR`): + `InterpolationMode` filter to use when resizing the image e.g. `InterpolationMode.BICUBIC`. + antialias (`bool`, *optional*, defaults to `True`): + Whether to use antialiasing when resizing the image. + """ + interpolation = interpolation if interpolation is not None else F.InterpolationMode.BILINEAR + if interpolation == F.InterpolationMode.LANCZOS: + logger.warning_once( + "You have used fast image processor with LANCZOS resample which not yet supported for torch.Tensor. " + "BICUBIC resample will be used as an alternative. Please fall back to slow image processor if you " + "want full consistency with the original model." + ) + interpolation = F.InterpolationMode.BICUBIC + + if size.longest_edge: + size = get_resize_output_image_size(image, resolution_max_side=size.longest_edge) + elif size.height and size.width: + size = (size.height, size.width) + else: + raise ValueError("size must be a dictionary with key 'longest_edge' or 'height' and 'width'.") + + return F.resize(image, size, interpolation=interpolation, antialias=antialias) + + def split_images( + self, + images: torch.Tensor, + max_image_size: dict[str, int], + interpolation: Optional["F.InterpolationMode"] = None, + ): + """ + Split an image into squares of side max_image_size and the original image resized to max_image_size. + That means that a single image becomes a sequence of images. + This is a "trick" to spend more compute on each image with no changes in the vision encoder. + 1) If one side of the original image is larger than `max_image_size`, resize it to `max_image_size` while preserving the aspect ratio. + 2) Divide the resulting image into `ceil(height / max_image_size)` x `ceil(width / max_image_size)` + sub-images of the same size each (image_size, image_size). Typically, 364x364. + 3) Returns the list of the crops and the original image, in addition to the number of splits for the height and the width. + Args: + images (`torch.Tensor`): + Images to split. + max_image_size (`Dict[str, int]`): + Maximum size of the output image. If the image is larger than this size, it will be split into + patches of this size, and the original image will be concatenated with the patches, resized to max_size. + interpolation (`InterpolationMode`, *optional*, defaults to `InterpolationMode.BILINEAR`): + `InterpolationMode` filter to use when resizing the image e.g. `InterpolationMode.BICUBIC`. + """ + batch_size, num_channels, height, width = images.size() + height_dim, width_dim = 2, 3 + + max_height = max_width = max_image_size["longest_edge"] + + frames = [] + if height > max_height or width > max_width: + # Calculate the number of splits + num_splits_h = math.ceil(height / max_height) + num_splits_w = math.ceil(width / max_width) + + # Split the images by height, then by width + frames = ( + images.unfold(height_dim, size=max_height, step=max_height) + .unfold(width_dim, size=max_width, step=max_width) + .contiguous() + .view(batch_size, num_channels, -1, max_height, max_width) + .permute(0, 2, 1, 3, 4) + ) # batch_size x n_frames x num_channels x height x width + + # For the global image at the end, we resize it to match the max_image_size, for cpu memory efficiency + global_image_height, global_image_width = max_height, max_width + images = self.resize( + images, SizeDict(height=global_image_height, width=global_image_width), interpolation=interpolation + ) + + frames = torch.cat((frames, images.unsqueeze(1)), dim=1) + else: + num_splits_h, num_splits_w = 0, 0 + frames = images.unsqueeze(1) + + num_splits_h = [num_splits_h] * batch_size + num_splits_w = [num_splits_w] * batch_size + + return frames, num_splits_h, num_splits_w + + def resize_for_vision_encoder( + self, + image: torch.Tensor, + vision_encoder_max_size: int, + interpolation: Optional["F.InterpolationMode"] = None, + ): + """ + Resize images to be multiples of `vision_encoder_max_size` while preserving the aspect ratio. + Args: + image (`torch.Tensor`): + Images to resize. + vision_encoder_max_size (`int`): + Maximum size of the output image. If the image is larger than this size, it will be split into + patches of this size, and the original image will be concatenated with the patches, resized to max_size. + interpolation (`InterpolationMode`, *optional*, defaults to `InterpolationMode.BILINEAR`): + `InterpolationMode` filter to use when resizing the image e.g. `InterpolationMode.BICUBIC`. + """ + height, width = image.size()[-2:] + + aspect_ratio = width / height + if width >= height: + width = math.ceil(width / vision_encoder_max_size) * vision_encoder_max_size + height = int(width / aspect_ratio) + height = math.ceil(height / vision_encoder_max_size) * vision_encoder_max_size + elif height > width: + height = math.ceil(height / vision_encoder_max_size) * vision_encoder_max_size + width = int(height * aspect_ratio) + width = math.ceil(width / vision_encoder_max_size) * vision_encoder_max_size + new_size = SizeDict(height=height, width=width) + return self.resize(image, size=new_size, interpolation=interpolation) + + def pad( + self, + image: torch.Tensor, + padded_size: tuple[int, int], + fill: int = 0, + return_pixel_mask: bool = True, + ): + original_size = image.shape[-2:] + padding_bottom = padded_size[0] - original_size[0] + padding_right = padded_size[1] - original_size[1] + + if padding_bottom < 0 or padding_right < 0: + raise ValueError( + f"Padding dimensions are negative. Please make sure that the padded size is larger than the " + f"original size. Got padded size: {padded_size}, original size: {original_size}." + ) + + # Only pad if necessary + if original_size != padded_size: + padding = (0, 0, padding_right, padding_bottom) + image = F.pad(image, padding, fill=fill, padding_mode="constant") + + # Make a pixel mask for the image, where 1 indicates a valid pixel and 0 indicates padding. + pixel_mask = None + if return_pixel_mask: + pixel_mask = torch.zeros_like(image[..., 0, :, :], dtype=torch.int64) + pixel_mask[: original_size[0], : original_size[1]] = 1 + + return image, pixel_mask + + @auto_docstring + def preprocess(self, images: ImageInput, **kwargs: Unpack[SmolVLMImageProcessorKwargs]) -> BatchFeature: + return super().preprocess(images, **kwargs) + + def _preprocess( + self, + images: list[list["torch.Tensor"]], + do_resize: bool, + size: SizeDict, + interpolation: Optional["F.InterpolationMode"], + do_rescale: bool, + rescale_factor: float, + do_normalize: bool, + image_mean: float | list[float] | None, + image_std: float | list[float] | None, + do_pad: bool | None, + do_image_splitting: bool | None, + max_image_size: dict[str, int] | None, + return_row_col_info: bool | None, + disable_grouping: bool | None, + return_tensors: str | TensorType | None, + **kwargs, + ) -> BatchFeature: + """ + Process a batch of images for the model. + """ + + grouped_images, grouped_images_index = group_images_by_shape( + images, is_nested=True, disable_grouping=disable_grouping + ) + resized_images_grouped = {} + for shape, stacked_images in grouped_images.items(): + if do_resize: + stacked_images = self.resize(stacked_images, size, interpolation=interpolation) + resized_images_grouped[shape] = stacked_images + resized_images = reorder_images(resized_images_grouped, grouped_images_index, is_nested=True) + + grouped_images, grouped_images_index = group_images_by_shape( + resized_images, is_nested=True, disable_grouping=disable_grouping + ) + split_images_grouped = {} + if do_image_splitting: + rows_grouped = {} + cols_grouped = {} + for shape, stacked_images in grouped_images.items(): + stacked_images = self.resize_for_vision_encoder( + stacked_images, max_image_size["longest_edge"], interpolation=interpolation + ) + stacked_images, rows, cols = self.split_images( + stacked_images, max_image_size=max_image_size, interpolation=interpolation + ) + split_images_grouped[shape] = stacked_images + rows_grouped[shape] = rows + cols_grouped[shape] = cols + processed_images = reorder_images(split_images_grouped, grouped_images_index, is_nested=True) + rows = reorder_images(rows_grouped, grouped_images_index, is_nested=True) + cols = reorder_images(cols_grouped, grouped_images_index, is_nested=True) + # flattenened the doubly nested list to a nested list + for i, group_images in enumerate(processed_images): + processed_images[i] = [image for sublist in group_images for image in sublist] + else: + for shape, stacked_images in grouped_images.items(): + # We square the images to max_image_size + stacked_images = self.resize( + image=stacked_images, + size=SizeDict(height=max_image_size["longest_edge"], width=max_image_size["longest_edge"]), + interpolation=interpolation, + ) + split_images_grouped[shape] = stacked_images + processed_images = reorder_images(split_images_grouped, grouped_images_index, is_nested=True) + rows = [[0] * len(images) for images in processed_images] + cols = [[0] * len(images) for images in processed_images] + # Group images by size for further processing + # Needed in case do_resize is False, or resize returns images with different sizes + grouped_images, grouped_images_index = group_images_by_shape( + processed_images, is_nested=True, disable_grouping=disable_grouping + ) + processed_images_grouped = {} + for shape, stacked_images in grouped_images.items(): + # Fused rescale and normalize + stacked_images = self.rescale_and_normalize( + stacked_images, do_rescale, rescale_factor, do_normalize, image_mean, image_std + ) + processed_images_grouped[shape] = stacked_images + processed_images = reorder_images(processed_images_grouped, grouped_images_index, is_nested=True) + if do_pad: + # Get max images per batch + max_num_images = max(len(images_) for images_ in processed_images) + max_height, max_width = get_max_height_width(processed_images) + num_channels = get_num_channels(processed_images) + device = get_device_from_images(processed_images) + + processed_images_padded = torch.zeros( + len(processed_images), + max_num_images, + *(num_channels, max_height, max_width), + device=device, + ) + pixel_attention_masks = torch.zeros( + len(processed_images), + max_num_images, + *(max_height, max_width), + device=device, + ) + for i, images in enumerate(processed_images): + for j, image in enumerate(images): + processed_images_padded[i, j], pixel_attention_masks[i, j] = self.pad( + image, (max_height, max_width) + ) + processed_images = processed_images_padded + + if do_pad: + data = {"pixel_values": processed_images, "pixel_attention_mask": pixel_attention_masks} + elif return_tensors == "pt": + data = {"pixel_values": torch.stack([torch.stack(images) for images in processed_images])} + else: + data = {"pixel_values": processed_images} + # This is needed for generating correct text inputs in the processor - we don't pad to the max number of images + encoding = BatchFeature(data=data, tensor_type=return_tensors) + + if return_row_col_info: + encoding["rows"] = rows + encoding["cols"] = cols + + return encoding + + def to_dict(self): + encoder_dict = super().to_dict() + encoder_dict.pop("_valid_processor_keys", None) + encoder_dict.pop("return_row_col_info", None) + return encoder_dict + + def get_number_of_image_patches(self, height: int, width: int, images_kwargs: dict): + """ + A utility that returns number of image patches for a given image size. + + Args: + height (`int`): + Height of the input image. + width (`int`): + Width of the input image. + images_kwargs (`dict`) + Any kwargs to override defaults of the image processor. + Returns: + `int`: Number of patches per image. + """ + do_image_splitting = images_kwargs.get("do_image_splitting", self.do_image_splitting) + max_image_size = images_kwargs.get("max_image_size", self.max_image_size) + size = images_kwargs.get("size", self.size) + + num_patches = num_rows = num_cols = 0 + if do_image_splitting: + height, width = _resize_output_size_rescale_to_max_len(height, width, max_len=size["longest_edge"]) + height, width = _resize_output_size_scale_below_upper_bound(height, width, max_len=MAX_IMAGE_SIZE) + aspect_ratio = width / height + + if width >= height: + resized_width = math.ceil(width / max_image_size["longest_edge"]) * max_image_size["longest_edge"] + resized_height = int(width / aspect_ratio) + resized_height = math.ceil(height / max_image_size["longest_edge"]) * max_image_size["longest_edge"] + elif height > width: + resized_height = math.ceil(height / max_image_size["longest_edge"]) * max_image_size["longest_edge"] + resized_width = int(height * aspect_ratio) + resized_width = math.ceil(width / max_image_size["longest_edge"]) * max_image_size["longest_edge"] + + max_height = max_width = max_image_size["longest_edge"] + if resized_height > max_height or resized_width > max_width: + # Calculate the number of splits + num_rows = math.ceil(resized_height / max_height) + num_cols = math.ceil(resized_width / max_width) + num_patches = num_rows * num_cols + 1 + + return num_patches, num_rows, num_cols + + +__all__ = ["SmolVLMImageProcessorFast"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/smolvlm/modeling_smolvlm.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/smolvlm/modeling_smolvlm.py new file mode 100644 index 0000000000000000000000000000000000000000..3c80c3aa7e41e2d56bc3b37ab097613f636101fe --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/smolvlm/modeling_smolvlm.py @@ -0,0 +1,915 @@ +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# This file was automatically generated from src/transformers/models/smolvlm/modular_smolvlm.py. +# Do NOT edit this file manually as any edits will be overwritten by the generation of +# the file from the modular. If any change should be done, please apply the change to the +# modular_smolvlm.py file directly. One of our CI enforces this. +# 🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨🚨 +# Copyright 2025 the HuggingFace Inc. team. All rights reserved. +# Written by Orr Zohar +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +from collections.abc import Callable +from dataclasses import dataclass + +import torch +from torch import nn + +from ...activations import ACT2FN +from ...cache_utils import Cache, DynamicCache +from ...generation import GenerationConfig, GenerationMixin +from ...masking_utils import create_bidirectional_mask +from ...modeling_flash_attention_utils import FlashAttentionKwargs +from ...modeling_layers import GradientCheckpointingLayer +from ...modeling_outputs import BaseModelOutput, BaseModelOutputWithPooling, ModelOutput +from ...modeling_utils import ALL_ATTENTION_FUNCTIONS, PreTrainedModel +from ...processing_utils import Unpack +from ...utils import ( + TransformersKwargs, + auto_docstring, + can_return_tuple, + logging, + torch_compilable_check, +) +from ...utils.generic import merge_with_config_defaults +from ...utils.output_capturing import capture_outputs +from ..auto import AutoModel +from .configuration_smolvlm import SmolVLMConfig, SmolVLMVisionConfig + + +logger = logging.get_logger(__name__) + + +@auto_docstring +class SmolVLMPreTrainedModel(PreTrainedModel): + config: SmolVLMConfig + base_model_prefix = "model" + input_modalities = ("image", "text") + supports_gradient_checkpointing = True + _no_split_modules = ["SmolVLMVisionAttention", "SmolVLMDecoderLayer"] + _skip_keys_device_placement = "past_key_values" + _supports_flash_attn = True + _supports_sdpa = True + _supports_flex_attn = True + _supports_attention_backend = True + + +class SmolVLMVisionEmbeddings(nn.Module): + """ + This is a modified version of `siglip.modelign_siglip.SiglipVisionEmbeddings` to enable images of variable + resolution. + + The modifications are adapted from [Patch n' Pack: NaViT, a Vision Transformer for any Aspect Ratio and Resolution](https://huggingface.co/papers/2307.06304) + which allows treating images in their native aspect ratio and without the need to resize them to the same + fixed size. In particular, we start from the original pre-trained SigLIP model + (which uses images of fixed-size square images) and adapt it by training on images of variable resolutions. + """ + + def __init__(self, config: SmolVLMVisionConfig): + super().__init__() + self.embed_dim = config.hidden_size + self.image_size = config.image_size + self.patch_size = config.patch_size + + self.patch_embedding = nn.Conv2d( + in_channels=config.num_channels, + out_channels=self.embed_dim, + kernel_size=self.patch_size, + stride=self.patch_size, + padding="valid", + ) + + self.num_patches_per_side = self.image_size // self.patch_size + self.num_patches = self.num_patches_per_side**2 + self.num_positions = self.num_patches + self.position_embedding = nn.Embedding(self.num_positions, self.embed_dim) + + def forward(self, pixel_values: torch.FloatTensor, patch_attention_mask: torch.BoolTensor) -> torch.Tensor: + batch_size, _, max_im_h, max_im_w = pixel_values.shape + + patch_embeds = self.patch_embedding(pixel_values) + embeddings = patch_embeds.flatten(2).transpose(1, 2) + + max_nb_patches_h, max_nb_patches_w = max_im_h // self.patch_size, max_im_w // self.patch_size + boundaries = torch.arange( + 1 / self.num_patches_per_side, 1.0, 1 / self.num_patches_per_side, device=pixel_values.device + ) + position_ids = torch.full( + size=(batch_size, max_nb_patches_h * max_nb_patches_w), fill_value=0, device=pixel_values.device + ) + + nb_patches_h = patch_attention_mask[:, :, 0].sum(dim=1) # (batch_size,) + nb_patches_w = patch_attention_mask[:, 0, :].sum(dim=1) # (batch_size,) + + step_h = 1.0 / nb_patches_h # (batch_size,) + step_w = 1.0 / nb_patches_w # (batch_size,) + + max_patches_h = patch_attention_mask.size(1) + max_patches_w = patch_attention_mask.size(2) + h_indices = torch.arange(max_patches_h, device=position_ids.device, dtype=torch.float32) + w_indices = torch.arange(max_patches_w, device=position_ids.device, dtype=torch.float32) + + fractional_coords_h = h_indices[None, :] * step_h[:, None] + fractional_coords_w = w_indices[None, :] * step_w[:, None] + + fractional_coords_h = torch.clamp(fractional_coords_h, max=(1.0 - 1e-6)) + fractional_coords_w = torch.clamp(fractional_coords_w, max=(1.0 - 1e-6)) + + fractional_coords_h = fractional_coords_h.to(pixel_values.dtype) + fractional_coords_w = fractional_coords_w.to(pixel_values.dtype) + + bucket_coords_h = torch.bucketize(fractional_coords_h, boundaries, right=True) + bucket_coords_w = torch.bucketize(fractional_coords_w, boundaries, right=True) + + pos_ids = bucket_coords_h[:, :, None] * self.num_patches_per_side + bucket_coords_w[:, None, :] + pos_ids = pos_ids.reshape(batch_size, -1) + + position_ids[patch_attention_mask.view(batch_size, -1)] = pos_ids[patch_attention_mask.view(batch_size, -1)] + + embeddings = embeddings + self.position_embedding(position_ids) + return embeddings + + +def eager_attention_forward( + module: nn.Module, + query: torch.Tensor, + key: torch.Tensor, + value: torch.Tensor, + attention_mask: torch.Tensor | None, + scaling: float, + dropout: float = 0.0, + **kwargs, +): + attn_weights = torch.matmul(query, key.transpose(-1, -2)) * scaling + if attention_mask is not None: + attn_weights = attn_weights + attention_mask + + attn_weights = nn.functional.softmax(attn_weights, dim=-1, dtype=torch.float32).to(query.dtype) + attn_weights = nn.functional.dropout(attn_weights, p=dropout, training=module.training) + + attn_output = torch.matmul(attn_weights, value) + attn_output = attn_output.transpose(1, 2).contiguous() + + return attn_output, attn_weights + + +class SmolVLMVisionAttention(nn.Module): + """Multi-headed attention from 'Attention Is All You Need' paper""" + + def __init__(self, config): + super().__init__() + self.config = config + self.embed_dim = config.hidden_size + self.num_heads = config.num_attention_heads + self.head_dim = self.embed_dim // self.num_heads + if self.head_dim * self.num_heads != self.embed_dim: + raise ValueError( + f"embed_dim must be divisible by num_heads (got `embed_dim`: {self.embed_dim} and `num_heads`:" + f" {self.num_heads})." + ) + self.scale = self.head_dim**-0.5 + self.dropout = config.attention_dropout + + self.k_proj = nn.Linear(self.embed_dim, self.embed_dim) + self.v_proj = nn.Linear(self.embed_dim, self.embed_dim) + self.q_proj = nn.Linear(self.embed_dim, self.embed_dim) + self.out_proj = nn.Linear(self.embed_dim, self.embed_dim) + + # Ignore copy + self.is_causal = False + + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.Tensor | None = None, + **kwargs, + ) -> tuple[torch.Tensor, torch.Tensor | None]: + """Input shape: Batch x Time x Channel""" + + batch_size, seq_length, embed_dim = hidden_states.shape + + queries = self.q_proj(hidden_states) + keys = self.k_proj(hidden_states) + values = self.v_proj(hidden_states) + + queries = queries.view(batch_size, seq_length, self.num_heads, self.head_dim).transpose(1, 2) + keys = keys.view(batch_size, seq_length, self.num_heads, self.head_dim).transpose(1, 2) + values = values.view(batch_size, seq_length, self.num_heads, self.head_dim).transpose(1, 2) + + attention_interface: Callable = ALL_ATTENTION_FUNCTIONS.get_interface( + self.config._attn_implementation, eager_attention_forward + ) + + attn_output, attn_weights = attention_interface( + self, + queries, + keys, + values, + attention_mask, + is_causal=self.is_causal, + scaling=self.scale, + dropout=0.0 if not self.training else self.dropout, + ) + + attn_output = attn_output.reshape(batch_size, seq_length, embed_dim).contiguous() + attn_output = self.out_proj(attn_output) + + return attn_output, attn_weights + + +class SmolVLMVisionMLP(nn.Module): + def __init__(self, config): + super().__init__() + self.config = config + self.activation_fn = ACT2FN[config.hidden_act] + self.fc1 = nn.Linear(config.hidden_size, config.intermediate_size) + self.fc2 = nn.Linear(config.intermediate_size, config.hidden_size) + + def forward(self, hidden_states: torch.Tensor) -> torch.Tensor: + hidden_states = self.fc1(hidden_states) + hidden_states = self.activation_fn(hidden_states) + hidden_states = self.fc2(hidden_states) + return hidden_states + + +class SmolVLMEncoderLayer(GradientCheckpointingLayer): + def __init__(self, config: SmolVLMVisionConfig): + super().__init__() + self.embed_dim = config.hidden_size + self.self_attn = SmolVLMVisionAttention(config) + self.layer_norm1 = nn.LayerNorm(self.embed_dim, eps=config.layer_norm_eps) + self.mlp = SmolVLMVisionMLP(config) + self.layer_norm2 = nn.LayerNorm(self.embed_dim, eps=config.layer_norm_eps) + + @auto_docstring + def forward( + self, + hidden_states: torch.Tensor, + attention_mask: torch.Tensor, + **kwargs: Unpack[TransformersKwargs], + ) -> torch.FloatTensor: + residual = hidden_states + + hidden_states = self.layer_norm1(hidden_states) + hidden_states, _ = self.self_attn( + hidden_states=hidden_states, + attention_mask=attention_mask, + **kwargs, + ) + hidden_states = residual + hidden_states + + residual = hidden_states + hidden_states = self.layer_norm2(hidden_states) + hidden_states = self.mlp(hidden_states) + hidden_states = residual + hidden_states + + return hidden_states + + +class SmolVLMEncoder(nn.Module): + """ + Transformer encoder consisting of `config.num_hidden_layers` self attention layers. Each layer is a + [`SmolVLMEncoderLayer`]. + + Args: + config: SmolVLMConfig + """ + + def __init__(self, config: SmolVLMConfig): + super().__init__() + self.config = config + self.layers = nn.ModuleList([SmolVLMEncoderLayer(config) for _ in range(config.num_hidden_layers)]) + self.gradient_checkpointing = False + + # Ignore copy + @auto_docstring + def forward( + self, + inputs_embeds, + attention_mask: torch.Tensor | None = None, + ) -> tuple | BaseModelOutput: + hidden_states = inputs_embeds + for encoder_layer in self.layers: + layer_outputs = encoder_layer( + hidden_states, + attention_mask, + ) + + hidden_states = layer_outputs + + return BaseModelOutput(last_hidden_state=hidden_states) + + +@auto_docstring( + custom_intro=""" + The SmolVLM Vision Transformer Model outputting raw image embedding. + """ +) +class SmolVLMVisionTransformer(SmolVLMPreTrainedModel): + config: SmolVLMVisionConfig + input_modalities = ("image",) + _supports_sdpa = True + _supports_flash_attn = True + _supports_flex_attn = True + _can_record_outputs = { + "hidden_states": SmolVLMEncoderLayer, + "attentions": SmolVLMVisionAttention, + } + + def __init__(self, config: SmolVLMVisionConfig): + super().__init__(config) + embed_dim = config.hidden_size + + self.embeddings = SmolVLMVisionEmbeddings(config) + self.encoder = SmolVLMEncoder(config) + self.patch_size = config.patch_size + self.post_layernorm = nn.LayerNorm(embed_dim, eps=config.layer_norm_eps) + + self.post_init() + + def get_input_embeddings(self): + return self.embeddings + + def set_input_embeddings(self, value): + self.embeddings = value + + @merge_with_config_defaults + @capture_outputs(tie_last_hidden_states=False) + def forward( + self, + pixel_values, + patch_attention_mask: torch.BoolTensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple | BaseModelOutput: + batch_size = pixel_values.size(0) + if patch_attention_mask is None: + patch_size = self.patch_size + patch_attention_mask = torch.ones( + ( + batch_size, + pixel_values.size(2) // patch_size, + pixel_values.size(3) // patch_size, + ) + ) + patch_attention_mask = patch_attention_mask.to(dtype=torch.bool, device=pixel_values.device) + + hidden_states = self.embeddings(pixel_values=pixel_values, patch_attention_mask=patch_attention_mask) + + patch_attention_mask = patch_attention_mask.view(batch_size, -1) + # Create the correct attention mask based on the attention implementation + patch_attention_mask = create_bidirectional_mask( + config=self.config, + inputs_embeds=hidden_states, + attention_mask=patch_attention_mask, + ) + + encoder_outputs: BaseModelOutput = self.encoder( + inputs_embeds=hidden_states, + attention_mask=patch_attention_mask, + ) + + last_hidden_state = encoder_outputs.last_hidden_state + last_hidden_state = self.post_layernorm(last_hidden_state) + + return BaseModelOutput( + last_hidden_state=last_hidden_state, + ) + + +@dataclass +@auto_docstring( + custom_intro=""" + Base class for SmolVLM model's outputs that may also contain a past key/values (to speed up sequential decoding). + """ +) +class SmolVLMBaseModelOutputWithPast(ModelOutput): + r""" + last_hidden_state (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`): + Sequence of hidden-states at the output of the last layer of the model. + If `past_key_values` is used only the last hidden-state of the sequences of shape `(batch_size, 1, + hidden_size)` is output. + past_key_values (`Cache`, *optional*, returned when `use_cache=True` is passed or when `config.use_cache=True`): + It is a [`~cache_utils.Cache`] instance. For more details, see our [kv cache guide](https://huggingface.co/docs/transformers/en/kv_cache). + + Contains pre-computed hidden-states (key and values in the self-attention blocks and optionally if + `config.is_encoder_decoder=True` in the cross-attention blocks) that can be used (see `past_key_values` + input) to speed up sequential decoding. + image_hidden_states (`tuple(torch.FloatTensor)`, *optional*): + Tuple of `torch.FloatTensor` (one for the output of the image embeddings, `(batch_size, num_images, + sequence_length, hidden_size)`. + image_hidden_states of the model produced by the vision encoder + """ + + last_hidden_state: torch.FloatTensor | None = None + past_key_values: Cache | None = None + hidden_states: tuple[torch.FloatTensor] | None = None + attentions: tuple[torch.FloatTensor] | None = None + image_hidden_states: tuple[torch.FloatTensor] | None = None + + +class SmolVLMSimpleMLP(nn.Module): + def __init__(self, config): + super().__init__() + input_size = config.vision_config.hidden_size * (config.scale_factor**2) + output_size = config.text_config.hidden_size + self.proj = nn.Linear(input_size, output_size, bias=False) + + def forward(self, x): + return self.proj(x) + + +class SmolVLMConnector(nn.Module): + def __init__(self, config): + super().__init__() + self.scale_factor = config.scale_factor + self.modality_projection = SmolVLMSimpleMLP(config) + + def pixel_shuffle(self, x, scale_factor=2): + bsz, seq, embed_dim = x.size() + height = width = int(seq**0.5) + x = x.view(bsz, height, width, embed_dim) + x = x.view(bsz, height, int(width / scale_factor), embed_dim * scale_factor) + x = x.permute(0, 2, 1, 3) + x = x.reshape(bsz, int(width / scale_factor), int(height / scale_factor), embed_dim * (scale_factor**2)) + x = x.permute(0, 2, 1, 3) + x = x.reshape(bsz, int(seq / (scale_factor**2)), embed_dim * (scale_factor**2)) + return x + + def forward(self, image_hidden_states): + image_hidden_states = self.pixel_shuffle(image_hidden_states, self.scale_factor) + image_hidden_states = self.modality_projection(image_hidden_states) + return image_hidden_states + + +@auto_docstring( + custom_intro=""" + SmolVLM model consisting of a SIGLIP vision encoder and Llama3 language decoder + """ +) +class SmolVLMModel(SmolVLMPreTrainedModel): + """ + A subclass of Idefics3Model. We do *not* remove or block the call to inputs_merger + in forward. Instead, we override inputs_merger here with custom logic. + """ + + def __init__(self, config: SmolVLMConfig): + super().__init__(config) + self.padding_idx = self.config.text_config.pad_token_id + self.vocab_size = self.config.text_config.vocab_size + + self.vision_model = SmolVLMVisionTransformer._from_config(config.vision_config) + self.connector = SmolVLMConnector(config) + self.text_model = AutoModel.from_config(config.text_config) + + self.image_seq_len = int( + ((config.vision_config.image_size // config.vision_config.patch_size) ** 2) / (config.scale_factor**2) + ) + self.image_token_id = self.config.image_token_id + + self.post_init() + + def get_input_embeddings(self): + return self.text_model.get_input_embeddings() + + def set_input_embeddings(self, value): + self.text_model.set_input_embeddings(value) + + def inputs_merger( + self, input_ids: torch.LongTensor, inputs_embeds: torch.Tensor, image_hidden_states: torch.Tensor + ): + """ + This method aims at merging the token embeddings with the image hidden states into one single sequence of vectors that are fed to the transformer LM. + The merging happens as follows: + - The text token sequence is: `tok_1 tok_2 tok_3 ... tok_4`. + - We get the image hidden states for the image through the vision encoder and that hidden state, after a pixel shuffle operation, is then projected into the text embedding space. + We thus have a sequence of image hidden states of size (1, image_seq_len, hidden_dim), where 1 is for batch_size of 1 image and hidden_dim is the hidden_dim of the LM transformer. + - The merging happens so that we obtain the following sequence: `vector_tok_1 vector_tok_2 vector_tok_3 vector_fake_tok_around_image {sequence of image_seq_len image hidden states} vector_fake_toke_around_image vector_tok_4`. That sequence is fed to the LM. + - To fit the format of that sequence, `input_ids`, `inputs_embeds`, `attention_mask` are all 3 adapted to insert the image hidden states. + """ + _, patch_size, _ = image_hidden_states.shape + + if input_ids is None: + image_mask = inputs_embeds == self.get_input_embeddings()( + torch.tensor(self.config.image_token_id, dtype=torch.long, device=inputs_embeds.device) + ) + image_mask = image_mask[..., 0] # slice off the hidden dim + else: + image_mask = input_ids == self.config.image_token_id + + num_image_tokens = image_mask.sum(dim=1) + torch_compilable_check( + torch.all(num_image_tokens % patch_size == 0), + "At least one sample has tokens not divisible by patch_size.", + ) + blocks_per_sample = num_image_tokens // patch_size + + offsets = torch.nn.functional.pad(blocks_per_sample.cumsum(dim=0), (1, 0), value=0) + block_offset = offsets[:-1] + row_cum = image_mask.cumsum(dim=-1) + chunk_idx = (row_cum - 1) // patch_size + local_idx = (row_cum - 1) % patch_size + block_idx = block_offset.unsqueeze(1) + chunk_idx + + image_embeds = torch.zeros_like(inputs_embeds) + image_embeds[image_mask] = image_hidden_states[block_idx[image_mask], local_idx[image_mask], :] + + merged_embeds = torch.where(image_mask.unsqueeze(-1), image_embeds, inputs_embeds) + return merged_embeds + + @can_return_tuple + @auto_docstring( + custom_intro="Encodes images into continuous embeddings that can be forwarded to the language model." + ) + def get_image_features( + self, + pixel_values: torch.FloatTensor, + pixel_attention_mask: torch.LongTensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple | BaseModelOutputWithPooling: + r""" + pixel_values (`torch.FloatTensor` of shape `(batch_size, num_channels, image_size, image_size)`): + The tensors corresponding to the input images. + pixel_attention_mask (`torch.LongTensor`, *optional*): + The attention mask indicating padded regions in the image. + """ + batch_size, num_images, num_channels, height, width = pixel_values.shape + pixel_values = pixel_values.to(dtype=self.dtype) # fp16 compatibility + pixel_values = pixel_values.view(batch_size * num_images, *pixel_values.shape[2:]) + + # Remove padding images - padding images are full 0. + nb_values_per_image = pixel_values.shape[1:].numel() + real_images_inds = (pixel_values == 0.0).sum(dim=(-1, -2, -3)) != nb_values_per_image + + # If no images, leave one empty image. + real_images_inds[0] |= ~torch.any(real_images_inds) + + pixel_values = pixel_values[real_images_inds].contiguous() + # Handle the vision attention mask + if pixel_attention_mask is None: + pixel_attention_mask = torch.ones( + size=[pixel_values.shape[i] for i in (0, 2, 3)], + dtype=torch.bool, + device=pixel_values.device, + ) + else: + # Remove padding images from the mask + pixel_attention_mask = pixel_attention_mask.view(batch_size * num_images, *pixel_attention_mask.shape[2:]) + pixel_attention_mask = pixel_attention_mask[real_images_inds].contiguous() + patch_size = self.config.vision_config.patch_size + patches_subgrid = pixel_attention_mask.unfold(dimension=1, size=patch_size, step=patch_size) + patches_subgrid = patches_subgrid.unfold(dimension=2, size=patch_size, step=patch_size) + patch_attention_mask = (patches_subgrid.sum(dim=(-1, -2)) > 0).bool() + + # Get sequence from the vision encoder + image_outputs = self.vision_model( + pixel_values=pixel_values, patch_attention_mask=patch_attention_mask, return_dict=True, **kwargs + ) + image_hidden_states = image_outputs.last_hidden_state + + # Modality projection & resampling + image_features = self.connector(image_hidden_states) + image_outputs.pooler_output = image_features + + return image_outputs + + @can_return_tuple + @auto_docstring( + custom_intro=""" + Inputs fed to the model can have an arbitrary number of images. To account for this, pixel_values fed to + the model have image padding -> (batch_size, max_num_images, 3, max_heights, max_widths) where + max_num_images is the maximum number of images among the batch_size samples in the batch. + Padding images are not needed beyond padding the pixel_values at the entrance of the model. + For efficiency, we only pass through the vision_model's forward the real images by + discarding the padding images i.e. pixel_values of size (image_batch_size, 3, height, width) where + image_batch_size would be 7 when num_images_per_sample=[1, 3, 1, 2] and max_num_images would be 3. + """ + ) + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.Tensor | None = None, + position_ids: torch.LongTensor | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.FloatTensor | None = None, + pixel_values: torch.FloatTensor | None = None, + pixel_attention_mask: torch.BoolTensor | None = None, + image_hidden_states: torch.FloatTensor | None = None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + cache_position: torch.LongTensor | None = None, + **kwargs: Unpack[FlashAttentionKwargs], + ) -> tuple | SmolVLMBaseModelOutputWithPast: + r""" + pixel_attention_mask (`torch.Tensor` of shape `(batch_size, image_size, image_size)`, *optional*): + Mask to avoid performing attention on padding pixel indices. + image_hidden_states (`torch.FloatTensor` of shape `(batch_size, num_channels, image_size, image_size)`): + The hidden states of the image encoder after modality projection. + """ + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + use_cache = use_cache if use_cache is not None else self.config.use_cache + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + if self.training and self.text_model.gradient_checkpointing and use_cache: + logger.warning_once( + "`use_cache=True` is incompatible with gradient checkpointing. Setting `use_cache=False`..." + ) + use_cache = False + + # retrieve input_ids and inputs_embeds + if input_ids is not None: + batch_size, seq_length = input_ids.shape + elif inputs_embeds is not None: + batch_size, seq_length, _ = inputs_embeds.shape + else: + raise ValueError("You have to specify either input_ids or inputs_embeds") + + if use_cache and past_key_values is None: + past_key_values = DynamicCache(config=self.config) + + if inputs_embeds is None: + inputs_embeds = self.text_model.get_input_embeddings()(input_ids).to(input_ids.device) + + # START VISUAL INPUTS INTEGRATION + if pixel_values is not None and image_hidden_states is not None: + raise ValueError("You cannot specify both pixel_values and image_hidden_states at the same time") + + if pixel_values is not None: + image_hidden_states = self.get_image_features( + pixel_values, pixel_attention_mask, return_dict=True + ).pooler_output + image_hidden_states = image_hidden_states.to(inputs_embeds.device) + elif image_hidden_states is not None: + image_hidden_states = image_hidden_states.to(dtype=self.dtype, device=inputs_embeds.device) + + if image_hidden_states is not None: + # When we generate, we don't want to replace the potential image_token_id that we generated by images + # that simply don't exist + inputs_embeds = self.inputs_merger( + input_ids=input_ids, + inputs_embeds=inputs_embeds, + image_hidden_states=image_hidden_states, + ) + + outputs = self.text_model( + inputs_embeds=inputs_embeds, + attention_mask=attention_mask, + position_ids=position_ids, + past_key_values=past_key_values, + use_cache=use_cache, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=True, + cache_position=cache_position, + **kwargs, + ) + + return SmolVLMBaseModelOutputWithPast( + last_hidden_state=outputs.last_hidden_state, + past_key_values=outputs.past_key_values, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + image_hidden_states=image_hidden_states, + ) + + +@dataclass +@auto_docstring( + custom_intro=""" + Base class for Idefics causal language model (or autoregressive) outputs. + """ +) +class SmolVLMCausalLMOutputWithPast(ModelOutput): + r""" + loss (`torch.FloatTensor` of shape `(1,)`, *optional*, returned when `labels` is provided): + Language modeling loss (for next-token prediction). + logits (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.vocab_size)`): + Prediction scores of the language modeling head (scores for each vocabulary token before SoftMax). + past_key_values (`Cache`, *optional*, returned when `use_cache=True` is passed or when `config.use_cache=True`): + It is a [`~cache_utils.Cache`] instance. For more details, see our [kv cache guide](https://huggingface.co/docs/transformers/en/kv_cache). + + Contains pre-computed hidden-states (key and values in the self-attention blocks) that can be used (see + `past_key_values` input) to speed up sequential decoding. + image_hidden_states (`tuple(torch.FloatTensor)`, *optional*): + Tuple of `torch.FloatTensor` (one for the output of the image embeddings, `(batch_size, num_images, + sequence_length, hidden_size)`. + image_hidden_states of the model produced by the vision encoder + """ + + loss: torch.FloatTensor | None = None + logits: torch.FloatTensor | None = None + past_key_values: Cache | None = None + hidden_states: tuple[torch.FloatTensor] | None = None + attentions: tuple[torch.FloatTensor] | None = None + image_hidden_states: tuple[torch.FloatTensor] | None = None + + +@auto_docstring( + custom_intro=""" + The SmolVLM Model with a language modeling head. It is made up a SigLIP vision encoder, with a language modeling head on top. + """ +) +class SmolVLMForConditionalGeneration(SmolVLMPreTrainedModel, GenerationMixin): + _tied_weights_keys = {"lm_head.weight": "model.text_model.embed_tokens.weight"} + + def __init__(self, config): + super().__init__(config) + self.model = SmolVLMModel(config) + self.image_token_id = self.config.image_token_id + self.lm_head = nn.Linear(config.text_config.hidden_size, config.text_config.vocab_size, bias=False) + self.vocab_size = config.text_config.vocab_size + self.model.text_model.generation_config = GenerationConfig.from_model_config(config) + + # Initialize weights and apply final processing + self.post_init() + + def get_input_embeddings(self): + return self.model.text_model.get_input_embeddings() + + def set_input_embeddings(self, value): + self.model.text_model.set_input_embeddings(value) + + @auto_docstring + def get_image_features( + self, + pixel_values: torch.FloatTensor, + pixel_attention_mask: torch.LongTensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple | BaseModelOutputWithPooling: + r""" + pixel_values (`torch.FloatTensor` of shape `(batch_size, num_channels, image_size, image_size)`): + The tensors corresponding to the input images. + pixel_attention_mask (`torch.LongTensor`, *optional*): + The attention mask indicating padded regions in the image. + """ + return self.model.get_image_features( + pixel_values=pixel_values, pixel_attention_mask=pixel_attention_mask, **kwargs + ) + + @can_return_tuple + @auto_docstring + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.Tensor | None = None, + position_ids: torch.LongTensor | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.FloatTensor | None = None, + pixel_values: torch.FloatTensor | None = None, + pixel_attention_mask: torch.BoolTensor | None = None, + image_hidden_states: torch.FloatTensor | None = None, + labels: torch.LongTensor | None = None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + cache_position: torch.LongTensor | None = None, + return_dict: bool | None = None, + logits_to_keep: int | torch.Tensor = 0, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple | SmolVLMCausalLMOutputWithPast: + r""" + pixel_attention_mask (`torch.Tensor` of shape `(batch_size, image_size, image_size)`, *optional*): + Mask to avoid performing attention on padding pixel indices. + image_hidden_states (`torch.FloatTensor` of shape `(batch_size, num_channels, image_size, image_size)`): + The hidden states of the image encoder after modality projection. + labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Labels for computing the masked language modeling loss. Indices should either be in `[0, ..., + config.vocab_size]` or `model.image_token_id`. Tokens with indices set to `model.image_token_id` are + ignored (masked), the loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]`. + + Example: + + ```python + >>> import httpx + >>> from io import BytesIO + >>> import torch + >>> from PIL import Image + >>> from io import BytesIO + + >>> from transformers import AutoProcessor, AutoModelForImageTextToText + >>> from transformers.image_utils import load_image + + >>> # Note that passing the image urls (instead of the actual pil images) to the processor is also possible + >>> image1 = load_image("https://cdn.britannica.com/61/93061-050-99147DCE/Statue-of-Liberty-Island-New-York-Bay.jpg") + >>> image2 = load_image("https://cdn.britannica.com/59/94459-050-DBA42467/Skyline-Chicago.jpg") + >>> image3 = load_image("https://cdn.britannica.com/68/170868-050-8DDE8263/Golden-Gate-Bridge-San-Francisco.jpg") + + >>> processor = AutoProcessor.from_pretrained("HuggingFaceTB/SmolVLM2-2.2B-Instruct") + >>> model = AutoModelForImageTextToText.from_pretrained("HuggingFaceTB/SmolVLM2-2.2B-Instruct", dtype=torch.bfloat16, device_map="auto") + + >>> # Create inputs + >>> messages = [ + ... { + ... "role": "user", + ... "content": [ + ... {"type": "video", "path": path/to/video}, + ... {"type": "text", "text": "What is happening in this video?"}, + ... ] + ... } + ... ] + + >>> inputs = processor.apply_chat_template([messages], add_generation_prompt=True) + + >>> # Generate + >>> generated_ids = model.generate(**inputs, max_new_tokens=256) + >>> generated_texts = processor.batch_decode(generated_ids, skip_special_tokens=True) + + >>> print(generated_texts) + ```""" + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + # decoder outputs consists of (dec_features, layer_state, dec_hidden, dec_attn) + outputs = self.model( + input_ids=input_ids, + attention_mask=attention_mask, + position_ids=position_ids, + past_key_values=past_key_values, + inputs_embeds=inputs_embeds, + pixel_values=pixel_values, + pixel_attention_mask=pixel_attention_mask, + image_hidden_states=image_hidden_states, + use_cache=use_cache, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + cache_position=cache_position, + return_dict=True, + **kwargs, + ) + + hidden_states = outputs[0] + # Only compute necessary logits, and do not upcast them to float if we are not computing the loss + slice_indices = slice(-logits_to_keep, None) if isinstance(logits_to_keep, int) else logits_to_keep + logits = self.lm_head(hidden_states[:, slice_indices, :]) + + loss = None + if labels is not None: + loss = self.loss_function( + logits=logits, labels=labels, vocab_size=self.config.text_config.vocab_size, **kwargs + ) + + return SmolVLMCausalLMOutputWithPast( + loss=loss, + logits=logits, + past_key_values=outputs.past_key_values, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + image_hidden_states=outputs.image_hidden_states, + ) + + def prepare_inputs_for_generation( + self, + input_ids, + past_key_values=None, + attention_mask=None, + inputs_embeds=None, + cache_position=None, + pixel_values=None, + pixel_attention_mask=None, + image_hidden_states=None, + logits_to_keep=None, + is_first_iteration=False, + **kwargs, + ): + # Overwritten -- there are mutually exclusive inputs (if the logic to make `image_hidden_states` take + # precedence is moved to the model, we can remove this fn) + + model_inputs = super().prepare_inputs_for_generation( + input_ids, + past_key_values=past_key_values, + attention_mask=attention_mask, + inputs_embeds=inputs_embeds, + cache_position=cache_position, + pixel_values=pixel_values, + pixel_attention_mask=pixel_attention_mask, + image_hidden_states=image_hidden_states, + logits_to_keep=logits_to_keep, + is_first_iteration=is_first_iteration, + **kwargs, + ) + + if image_hidden_states is not None or not is_first_iteration: + model_inputs["pixel_values"] = None + model_inputs["pixel_attention_mask"] = None + + return model_inputs + + +__all__ = ["SmolVLMForConditionalGeneration", "SmolVLMPreTrainedModel", "SmolVLMModel", "SmolVLMVisionTransformer"] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/smolvlm/modular_smolvlm.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/smolvlm/modular_smolvlm.py new file mode 100644 index 0000000000000000000000000000000000000000..179b809c6b9deaed82c1b03c22e292a8879c40ad --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/smolvlm/modular_smolvlm.py @@ -0,0 +1,422 @@ +# Copyright 2025 the HuggingFace Inc. team. All rights reserved. +# Written by Orr Zohar +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import torch +from torch import nn + +from ...cache_utils import Cache, DynamicCache +from ...generation import GenerationConfig +from ...modeling_flash_attention_utils import FlashAttentionKwargs +from ...modeling_outputs import BaseModelOutputWithPooling +from ...processing_utils import Unpack +from ...utils import TransformersKwargs, auto_docstring, can_return_tuple, logging, torch_compilable_check +from ..idefics3.configuration_idefics3 import Idefics3Config, Idefics3VisionConfig +from ..idefics3.image_processing_idefics3 import Idefics3ImageProcessor +from ..idefics3.image_processing_idefics3_fast import Idefics3ImageProcessorFast +from ..idefics3.modeling_idefics3 import ( + Idefics3BaseModelOutputWithPast, + Idefics3ForConditionalGeneration, + Idefics3Model, + Idefics3PreTrainedModel, + Idefics3VisionTransformer, +) + + +logger = logging.get_logger(__name__) + + +class SmolVLMVisionConfig(Idefics3VisionConfig): + r""" + This is the configuration class to store the configuration of a [`SmolVLMVisionModel`]. It is used to instantiate a + SmolVLM vision encoder according to the specified arguments, defining the model architecture. Instantiating a + configuration with the defaults will yield a similar configuration to that of the SigLIP checkpoint + [google/siglip-so400m-patch14-384](https://huggingface.co/google/siglip-so400m-patch14-384) used in SmolVLM + [HuggingFaceTB/SmolVLM2-2.2B-Instruct](https://huggingface.co/HuggingFaceTB/SmolVLM2-2.2B-Instruct). + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + hidden_size (`int`, *optional*, defaults to 1152): + Dimensionality of the encoder layers and the pooler layer. + intermediate_size (`int`, *optional*, defaults to 3072): + Dimensionality of the "intermediate" (i.e., feed-forward) layer in the Transformer encoder. + num_hidden_layers (`int`, *optional*, defaults to 12): + Number of hidden layers in the Transformer encoder. + num_attention_heads (`int`, *optional*, defaults to 16): + Number of attention heads for each attention layer in the Transformer encoder. + num_channels (`int`, *optional*, defaults to 3): + Number of channels in the input images. + image_size (`int`, *optional*, defaults to 224): + The size (resolution) of each image. + patch_size (`int`, *optional*, defaults to 32): + The size (resolution) of each patch. + hidden_act (`str` or `function`, *optional*, defaults to `"gelu_pytorch_tanh"`): + The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`, + `"relu"`, `"selu"` and `"gelu_new"` `"quick_gelu"` are supported. + layer_norm_eps (`float`, *optional*, defaults to 1e-06): + The epsilon used by the layer normalization layers. + attention_dropout (`float`, *optional*, defaults to 0.0): + The dropout ratio for the attention probabilities. + initializer_range (`float`, *optional*, defaults to 0.02): + The standard deviation of the truncated_normal_initializer for initializing all weight matrices. + + Example: + + ```python + >>> from transformers.models.smolvlm.modeling_smolvlm import SmolVLMVisionTransformer + >>> from transformers.models.smolvlm.configuration_smolvlm import SmolVLMVisionConfig + + >>> # Initializing a SmolVLMVisionConfig with google/siglip-so400m-patch14-384 style configuration + >>> configuration = SmolVLMVisionConfig() + + >>> # Initializing a SmolVLMVisionTransformer (with random weights) from the google/siglip-so400m-patch14-384 style configuration + >>> model = SmolVLMVisionTransformer(configuration) + + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "smolvlm_vision" + + +class SmolVLMPreTrainedModel(Idefics3PreTrainedModel): + pass + + +class SmolVLMVisionTransformer(Idefics3VisionTransformer): + pass + + +class SmolVLMConfig(Idefics3Config): + r""" + This is the configuration class to store the configuration of a [`SmolVLMModel`]. It is used to instantiate a + SmolVLM model according to the specified arguments, defining the model architecture. Instantiating a + configuration with the defaults will yield a similar configuration to that of the model of the SmolVLM + [HuggingFaceTB/SmolVLM2-2.2B-Instruct](https://huggingface.co/HuggingFaceTB/SmolVLM2-2.2B-Instruct) architecture. + + Configuration objects inherit from [`PreTrainedConfig`] and can be used to control the model outputs. Read the + documentation from [`PreTrainedConfig`] for more information. + + Args: + use_cache (`bool`, *optional*, defaults to `True`): + Whether or not the model should cache the key/value pairs of the attention mechanism. Only + relevant if `config.is_decoder=True`. + image_token_id (`int`, *optional*, defaults to 128257): + The id of the "image" token. + tie_word_embeddings (`bool`, *optional*, defaults to `False`): + Whether or not to tie the word embeddings with the token embeddings. + vision_config (`IdeficsVisionConfig` or `dict`, *optional*, defaults to `IdeficsVisionConfig`): + Custom vision config or dict for the vision tower + text_config (`PreTrainedConfig` or `dict`, *optional*, defaults to `LlamaConfig`): + Custom text config or dict for the text model + scale_factor (`int`, *optional*, defaults to 2): + The scale factor for the image encoder. + pad_token_id (`int`, *optional*, defaults to 128002): + The id of the padding token. + + Example: + ```python + >>> from transformers import SmolVLMModel, SmolVLMConfig + >>> # Initializing configuration + >>> configuration = SmolVLMConfig() + >>> # Initializing a model from the configuration + >>> model = SmolVLMModel(configuration) + >>> # Accessing the model configuration + >>> configuration = model.config + ```""" + + model_type = "smolvlm" + + +class SmolVLMImageProcessor(Idefics3ImageProcessor): + pass + + +class SmolVLMImageProcessorFast(Idefics3ImageProcessorFast): + pass + + +class SmolVLMBaseModelOutputWithPast(Idefics3BaseModelOutputWithPast): + pass + + +class SmolVLMModel(Idefics3Model): + """ + A subclass of Idefics3Model. We do *not* remove or block the call to inputs_merger + in forward. Instead, we override inputs_merger here with custom logic. + """ + + def inputs_merger( + self, input_ids: torch.LongTensor, inputs_embeds: torch.Tensor, image_hidden_states: torch.Tensor + ): + _, patch_size, _ = image_hidden_states.shape + + if input_ids is None: + image_mask = inputs_embeds == self.get_input_embeddings()( + torch.tensor(self.config.image_token_id, dtype=torch.long, device=inputs_embeds.device) + ) + image_mask = image_mask[..., 0] # slice off the hidden dim + else: + image_mask = input_ids == self.config.image_token_id + + num_image_tokens = image_mask.sum(dim=1) + torch_compilable_check( + torch.all(num_image_tokens % patch_size == 0), + "At least one sample has tokens not divisible by patch_size.", + ) + blocks_per_sample = num_image_tokens // patch_size + + offsets = torch.nn.functional.pad(blocks_per_sample.cumsum(dim=0), (1, 0), value=0) + block_offset = offsets[:-1] + row_cum = image_mask.cumsum(dim=-1) + chunk_idx = (row_cum - 1) // patch_size + local_idx = (row_cum - 1) % patch_size + block_idx = block_offset.unsqueeze(1) + chunk_idx + + image_embeds = torch.zeros_like(inputs_embeds) + image_embeds[image_mask] = image_hidden_states[block_idx[image_mask], local_idx[image_mask], :] + + merged_embeds = torch.where(image_mask.unsqueeze(-1), image_embeds, inputs_embeds) + return merged_embeds + + @can_return_tuple + @auto_docstring( + custom_intro="Encodes images into continuous embeddings that can be forwarded to the language model." + ) + def get_image_features( + self, + pixel_values: torch.FloatTensor, + pixel_attention_mask: torch.LongTensor | None = None, + **kwargs: Unpack[TransformersKwargs], + ) -> tuple | BaseModelOutputWithPooling: + r""" + pixel_values (`torch.FloatTensor` of shape `(batch_size, num_channels, image_size, image_size)`): + The tensors corresponding to the input images. + pixel_attention_mask (`torch.LongTensor`, *optional*): + The attention mask indicating padded regions in the image. + """ + batch_size, num_images, num_channels, height, width = pixel_values.shape + pixel_values = pixel_values.to(dtype=self.dtype) # fp16 compatibility + pixel_values = pixel_values.view(batch_size * num_images, *pixel_values.shape[2:]) + + # Remove padding images - padding images are full 0. + nb_values_per_image = pixel_values.shape[1:].numel() + real_images_inds = (pixel_values == 0.0).sum(dim=(-1, -2, -3)) != nb_values_per_image + + # If no images, leave one empty image. + real_images_inds[0] |= ~torch.any(real_images_inds) + + pixel_values = pixel_values[real_images_inds].contiguous() + # Handle the vision attention mask + if pixel_attention_mask is None: + pixel_attention_mask = torch.ones( + size=[pixel_values.shape[i] for i in (0, 2, 3)], + dtype=torch.bool, + device=pixel_values.device, + ) + else: + # Remove padding images from the mask + pixel_attention_mask = pixel_attention_mask.view(batch_size * num_images, *pixel_attention_mask.shape[2:]) + pixel_attention_mask = pixel_attention_mask[real_images_inds].contiguous() + patch_size = self.config.vision_config.patch_size + patches_subgrid = pixel_attention_mask.unfold(dimension=1, size=patch_size, step=patch_size) + patches_subgrid = patches_subgrid.unfold(dimension=2, size=patch_size, step=patch_size) + patch_attention_mask = (patches_subgrid.sum(dim=(-1, -2)) > 0).bool() + + # Get sequence from the vision encoder + image_outputs = self.vision_model( + pixel_values=pixel_values, patch_attention_mask=patch_attention_mask, return_dict=True, **kwargs + ) + image_hidden_states = image_outputs.last_hidden_state + + # Modality projection & resampling + image_features = self.connector(image_hidden_states) + image_outputs.pooler_output = image_features + + return image_outputs + + @can_return_tuple + @auto_docstring( + custom_intro=""" + Inputs fed to the model can have an arbitrary number of images. To account for this, pixel_values fed to + the model have image padding -> (batch_size, max_num_images, 3, max_heights, max_widths) where + max_num_images is the maximum number of images among the batch_size samples in the batch. + Padding images are not needed beyond padding the pixel_values at the entrance of the model. + For efficiency, we only pass through the vision_model's forward the real images by + discarding the padding images i.e. pixel_values of size (image_batch_size, 3, height, width) where + image_batch_size would be 7 when num_images_per_sample=[1, 3, 1, 2] and max_num_images would be 3. + """ + ) + def forward( + self, + input_ids: torch.LongTensor | None = None, + attention_mask: torch.Tensor | None = None, + position_ids: torch.LongTensor | None = None, + past_key_values: Cache | None = None, + inputs_embeds: torch.FloatTensor | None = None, + pixel_values: torch.FloatTensor | None = None, + pixel_attention_mask: torch.BoolTensor | None = None, + image_hidden_states: torch.FloatTensor | None = None, + use_cache: bool | None = None, + output_attentions: bool | None = None, + output_hidden_states: bool | None = None, + return_dict: bool | None = None, + cache_position: torch.LongTensor | None = None, + **kwargs: Unpack[FlashAttentionKwargs], + ) -> tuple | SmolVLMBaseModelOutputWithPast: + output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions + output_hidden_states = ( + output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states + ) + use_cache = use_cache if use_cache is not None else self.config.use_cache + return_dict = return_dict if return_dict is not None else self.config.use_return_dict + + if self.training and self.text_model.gradient_checkpointing and use_cache: + logger.warning_once( + "`use_cache=True` is incompatible with gradient checkpointing. Setting `use_cache=False`..." + ) + use_cache = False + + # retrieve input_ids and inputs_embeds + if input_ids is not None: + batch_size, seq_length = input_ids.shape + elif inputs_embeds is not None: + batch_size, seq_length, _ = inputs_embeds.shape + else: + raise ValueError("You have to specify either input_ids or inputs_embeds") + + if use_cache and past_key_values is None: + past_key_values = DynamicCache(config=self.config) + + if inputs_embeds is None: + inputs_embeds = self.text_model.get_input_embeddings()(input_ids).to(input_ids.device) + + # START VISUAL INPUTS INTEGRATION + if pixel_values is not None and image_hidden_states is not None: + raise ValueError("You cannot specify both pixel_values and image_hidden_states at the same time") + + if pixel_values is not None: + image_hidden_states = self.get_image_features( + pixel_values, pixel_attention_mask, return_dict=True + ).pooler_output + image_hidden_states = image_hidden_states.to(inputs_embeds.device) + elif image_hidden_states is not None: + image_hidden_states = image_hidden_states.to(dtype=self.dtype, device=inputs_embeds.device) + + if image_hidden_states is not None: + # When we generate, we don't want to replace the potential image_token_id that we generated by images + # that simply don't exist + inputs_embeds = self.inputs_merger( + input_ids=input_ids, + inputs_embeds=inputs_embeds, + image_hidden_states=image_hidden_states, + ) + + outputs = self.text_model( + inputs_embeds=inputs_embeds, + attention_mask=attention_mask, + position_ids=position_ids, + past_key_values=past_key_values, + use_cache=use_cache, + output_attentions=output_attentions, + output_hidden_states=output_hidden_states, + return_dict=True, + cache_position=cache_position, + **kwargs, + ) + + return SmolVLMBaseModelOutputWithPast( + last_hidden_state=outputs.last_hidden_state, + past_key_values=outputs.past_key_values, + hidden_states=outputs.hidden_states, + attentions=outputs.attentions, + image_hidden_states=image_hidden_states, + ) + + +class SmolVLMForConditionalGeneration(Idefics3ForConditionalGeneration): + _tied_weights_keys = {"lm_head.weight": "model.text_model.embed_tokens.weight"} + + def __init__(self, config): + super().__init__(config) + self.model = SmolVLMModel(config) + self.model.text_model.generation_config = GenerationConfig.from_model_config(config) + self.lm_head = nn.Linear(config.text_config.hidden_size, config.text_config.vocab_size, bias=False) + self.post_init() + + def forward(self, **super_kwargs): + r""" + pixel_attention_mask (`torch.Tensor` of shape `(batch_size, image_size, image_size)`, *optional*): + Mask to avoid performing attention on padding pixel indices. + image_hidden_states (`torch.FloatTensor` of shape `(batch_size, num_channels, image_size, image_size)`): + The hidden states of the image encoder after modality projection. + labels (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*): + Labels for computing the masked language modeling loss. Indices should either be in `[0, ..., + config.vocab_size]` or `model.image_token_id`. Tokens with indices set to `model.image_token_id` are + ignored (masked), the loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]`. + + Example: + + ```python + >>> import httpx + >>> from io import BytesIO + >>> import torch + >>> from PIL import Image + >>> from io import BytesIO + + >>> from transformers import AutoProcessor, AutoModelForImageTextToText + >>> from transformers.image_utils import load_image + + >>> # Note that passing the image urls (instead of the actual pil images) to the processor is also possible + >>> image1 = load_image("https://cdn.britannica.com/61/93061-050-99147DCE/Statue-of-Liberty-Island-New-York-Bay.jpg") + >>> image2 = load_image("https://cdn.britannica.com/59/94459-050-DBA42467/Skyline-Chicago.jpg") + >>> image3 = load_image("https://cdn.britannica.com/68/170868-050-8DDE8263/Golden-Gate-Bridge-San-Francisco.jpg") + + >>> processor = AutoProcessor.from_pretrained("HuggingFaceTB/SmolVLM2-2.2B-Instruct") + >>> model = AutoModelForImageTextToText.from_pretrained("HuggingFaceTB/SmolVLM2-2.2B-Instruct", dtype=torch.bfloat16, device_map="auto") + + >>> # Create inputs + >>> messages = [ + ... { + ... "role": "user", + ... "content": [ + ... {"type": "video", "path": path/to/video}, + ... {"type": "text", "text": "What is happening in this video?"}, + ... ] + ... } + ... ] + + >>> inputs = processor.apply_chat_template([messages], add_generation_prompt=True) + + >>> # Generate + >>> generated_ids = model.generate(**inputs, max_new_tokens=256) + >>> generated_texts = processor.batch_decode(generated_ids, skip_special_tokens=True) + + >>> print(generated_texts) + ```""" + super().forward(**super_kwargs) + + +__all__ = [ + "SmolVLMVisionConfig", + "SmolVLMConfig", + "SmolVLMImageProcessor", + "SmolVLMImageProcessorFast", + "SmolVLMForConditionalGeneration", + "SmolVLMPreTrainedModel", + "SmolVLMModel", + "SmolVLMVisionTransformer", +] diff --git a/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/smolvlm/processing_smolvlm.py b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/smolvlm/processing_smolvlm.py new file mode 100644 index 0000000000000000000000000000000000000000..21d7f24466a5cc5d821ef437188db9b7f42c02f8 --- /dev/null +++ b/miniconda3/envs/ladir/lib/python3.10/site-packages/transformers/models/smolvlm/processing_smolvlm.py @@ -0,0 +1,345 @@ +# Copyright 2025 The HuggingFace Inc. team. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +""" +Processor class for SmolVLM. +""" + +from datetime import timedelta +from typing import TYPE_CHECKING, Union + +from ...feature_extraction_utils import BatchFeature +from ...image_utils import ImageInput, make_nested_list_of_images +from ...processing_utils import AllKwargsForChatTemplate, ProcessingKwargs, ProcessorMixin, Unpack +from ...tokenization_utils_base import BatchEncoding, TextInput +from ...utils import auto_docstring, is_num2words_available, is_vision_available, logging +from ...video_utils import VideoInput + + +if is_vision_available(): + from .video_processing_smolvlm import ( + DEFAULT_MEDIA_OUTTRO, + DEFAULT_VIDEO_INTRO, + FRAME_TIMESTAMP_MESSAGE, + ) + +if TYPE_CHECKING: + from ...tokenization_utils_base import PreTokenizedInput + +logger = logging.get_logger(__name__) + + +if is_num2words_available(): + from num2words import num2words +else: + num2words = None + + +# The correct chat template to be used for videos after #38105 +DEFAULT_CHAT_TEMPLATE = "<|im_start|>{% for message in messages %}{{message['role'] | capitalize}}{% if message['content'][0]['type'] == 'image' %}{{':'}}{% else %}{{': '}}{% endif %}{% for line in message['content'] %}{% if line['type'] == 'text' %}{{line['text']}}{% elif line['type'] == 'image' %}{{ '' }}{% elif line['type'] == 'video' %}{{ '