--- license: mit language: - en library_name: gguf pipeline_tag: text-classification tags: - gguf - openvino - llama.cpp - decision-model - yes-no - zero-shot-classification - cpu - local - on-device - jev ---

jevos logo

jevos-v4

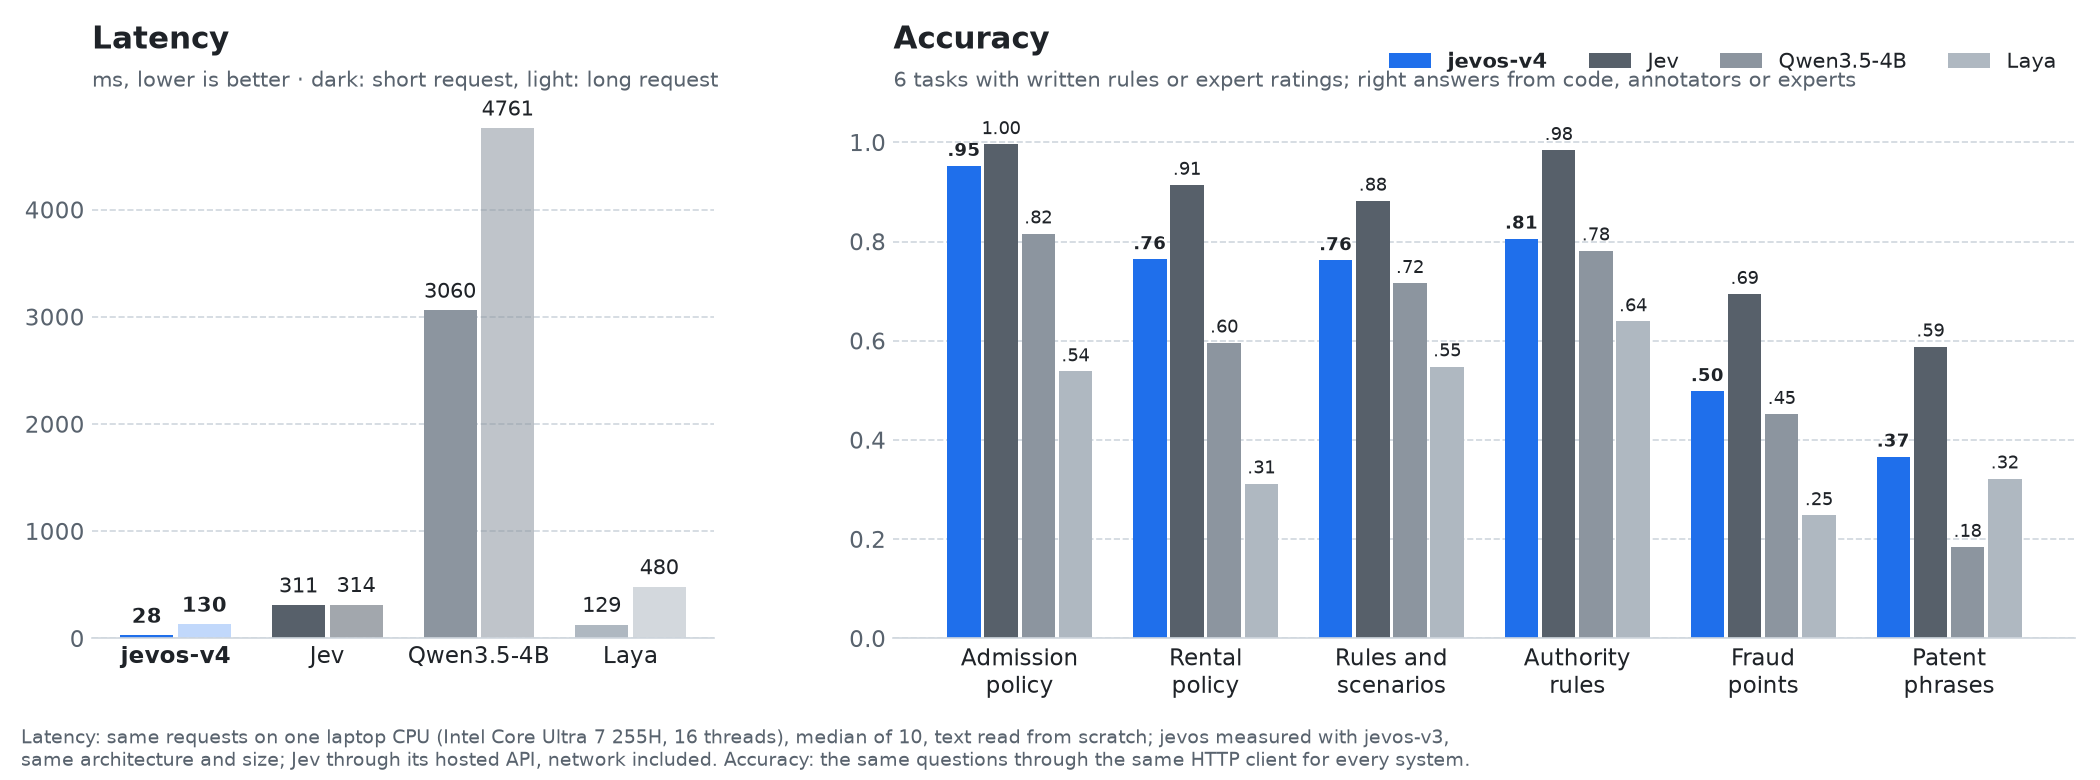
**Decisions on a laptop CPU in 28–130 ms.** Send a text and a question (yes/no, multiple choice or a score) and get back the probability of each answer, in TypeSafe Jev's API, on your own machine. Free and open source: an alternative to Jev that runs locally. *Same Snake game, same questions for both: jevos-v4 on a laptop answers in about 20 ms, Jev's cloud API in about 350 ms (mostly the network round trip), so the local snake makes many more moves in the same time.* ## Files | File | What it is | |---|---| | `model/` | the OpenVINO INT8 model that the `jev` binary runs (CPU) | | `jevos-v4-q4_k_m.gguf` | the same model as 4-bit GGUF, for llama.cpp and the tools built on it | | `jevos-v4-q8_0.gguf` | the same model as 8-bit GGUF | These are the same files as the [jevos-v4 release on GitHub](https://github.com/feder-cr/jev/releases/tag/jevos-v4); the SHA-256 of each is in that release's `SHA256SUMS.txt`. ## Quickstart Get the `jev` binary for your system from the [GitHub release](https://github.com/feder-cr/jev/releases/tag/jevos-v4) (Windows, Linux, macOS on Apple silicon), then put the model next to it: ```bash tar -xzf jev-linux-x64.tar.gz # Windows: unzip jev-windows-x64.zip hf download feder-cr/jev --include "model/*" --local-dir jev cd jev ./jev serve # Windows: jev.exe serve ``` ```bash curl http://127.0.0.1:8017/v1/systemone -H 'Content-Type: application/json' -d '{ "model": "jev-latest", "state": "I was charged twice for the same order.", "questions": {"billing": {"type": "noul", "instructions": "Is this a billing problem?"}}}' ``` ```json {"model": "jevos-v4", "answers": {"billing": {"type": "noul", "noul": 0.94}}, "usage": {"input_tokens": 27, "output_tokens": 0}} ``` One binary, CPU only, no Python. ## Benchmarks Latency on a short / long request: jevos-v4 28 / 130 ms; Jev 311 / 314 ms; Qwen3.5-4B 3,060 / 4,761 ms; Laya 129 / 480 ms. Accuracy on 6 tasks (Admission policy, Rental policy, Rules and scenarios, Authority rules, Fraud points, Patent phrases): jevos-v4 0.95, 0.76, 0.76, 0.81, 0.50, 0.37; Jev 1.00, 0.91, 0.88, 0.98, 0.69, 0.59; Qwen3.5-4B 0.82, 0.60, 0.72, 0.78, 0.45, 0.18; Laya 0.54, 0.31, 0.55, 0.64, 0.25, 0.32 Same questions for every system, through the same HTTP client. Latency is the median of 10 requests on an Intel Core Ultra 7 255H laptop, 16 threads, each text read from scratch. No task text was used to train jevos; five of the six sets helped choose the released checkpoint. | | **jevos-v4** | Jev | Laya | |---|:---:|:---:|:---:| | Yes/no questions | ✓ | ✓ | ✓ | | Multiple choice | ✓ | ✓ | ✓ | | Scores | ✓ (early) | ✓ | ✓ | | Runs on | your machine | cloud | your machine | | Cost | free | per token | free | | Context | 8,192 tokens | not stated | 512 tokens | jevos-v4 is much faster than the cloud API and free, but less accurate than Jev on the harder tasks above (fraud points, patent phrases): check it on your own questions before relying on it. ## API `POST /v1/systemone`, in TypeSafe Jev's wire format: code written for Jev's SDK works unchanged for yes/no questions. One request can ask several questions about the same text, which is read once: ```json { "model": "jev-latest", "state": {"item": "wireless mouse", "customer_message": "The box arrived empty. This is the second time!"}, "questions": { "refund": {"type": "noul", "instructions": "Our policy refunds items reported missing within 30 days of delivery. Should this customer get a refund?"}, "team": {"type": "choice", "instructions": "Which team should handle this message?", "criteria": {"billing": "payments, refunds", "shipping": "deliveries, missing parcels", "tech": "a product that does not work"}}, "anger": {"type": "score", "instructions": "How angry is the customer?", "criteria": ["calm", "annoyed", "angry", "furious"]} } } ``` A `noul` returns P(yes); a `choice` the most probable option; a `score` the expected level. Choices and scores also return a probability per answer and a `confidence`: when it is low, send the case to a person. Put the rule in the question, and do sums in code. Options, memory use and building from source are in the [README on GitHub](https://github.com/feder-cr/jev#readme); guides and measurements are in the [wiki](https://github.com/feder-cr/jev/wiki). ## License and authors MIT. Built by [Federico Elia (@feder-cr)](https://github.com/feder-cr) together with [Loris Salsi (@LosaLosSantos)](https://github.com/LosaLosSantos).