--- base_model: CSWRY/VOSR base_model_relation: quantized license: apache-2.0 pipeline_tag: image-to-image library_name: onnx tags: - onnx - moonbox - vosr - super-resolution - image-upscaling - image-restoration - upscaling - image-to-image - diffusion - one-step --- # VOSR 2.0 ONNX ONNX builds of [VOSR 2.0](https://github.com/cswry/VOSR), made by Moonbox for on-device use with ONNX Runtime (CUDA, DirectML, CPU). Each precision is a folder with one graph per part of the pipeline; large weights sit next to each graph as ONNX external data (`*.onnx.data`), so keep a folder's files together. ## Files The last column is how far each graph's output is from the original PyTorch model run in fp32 on the same inputs (relative RMS error). fp32 is the yardstick because the original's own bf16 run is not exact either. Image-quality scores are added as each precision passes the image eval. | Precision | File | Size | sha256 | Checked against fp32 | |---|---|---|---|---| | int8 | [`int8/image_encoder/model.onnx`](https://huggingface.co/moonbox-dev/VOSR-ONNX/blob/main/int8/image_encoder/model.onnx) | 460.5 MB | `991f96af4a0d` | 1.8e-03 (fp16 graph) | | int8 | [`int8/transformer/model.onnx`](https://huggingface.co/moonbox-dev/VOSR-ONNX/blob/main/int8/transformer/model.onnx) | 1.41 GB | `e38ab9630515` | 36.7 / 35.1 dB vs fp32 on Set14 / BSD100 (int8 weights) | | int8 | [`int8/vae_decoder/model.onnx`](https://huggingface.co/moonbox-dev/VOSR-ONNX/blob/main/int8/vae_decoder/model.onnx) | 50.7 MB | `3ca755f97a8d` | 2.9e-04 (fp16 graph) | | int8 | [`int8/vae_encoder/model.onnx`](https://huggingface.co/moonbox-dev/VOSR-ONNX/blob/main/int8/vae_encoder/model.onnx) | 38.7 MB | `c3efac4d5f17` | 3.1e-04 (fp16 graph) | | int4 | [`int4/image_encoder/model.onnx`](https://huggingface.co/moonbox-dev/VOSR-ONNX/blob/main/int4/image_encoder/model.onnx) | 460.5 MB | `991f96af4a0d` | 1.8e-03 (fp16 graph) | | int4 | [`int4/transformer/model.onnx`](https://huggingface.co/moonbox-dev/VOSR-ONNX/blob/main/int4/transformer/model.onnx) | 912.1 MB | `6c732b4943d6` | 30.6 / 30.1 dB vs fp32 on Set14 / BSD100 (4-bit MatMul weights) | | int4 | [`int4/vae_decoder/model.onnx`](https://huggingface.co/moonbox-dev/VOSR-ONNX/blob/main/int4/vae_decoder/model.onnx) | 50.7 MB | `3ca755f97a8d` | 2.9e-04 (fp16 graph) | | int4 | [`int4/vae_encoder/model.onnx`](https://huggingface.co/moonbox-dev/VOSR-ONNX/blob/main/int4/vae_encoder/model.onnx) | 38.7 MB | `c3efac4d5f17` | 3.1e-04 (fp16 graph) | ## How to run VOSR 2.0 is a one-step generative 4x upscaler (CVPR 2026): a 1.4 B diffusion transformer that restores a picture in a single step, conditioned on the bicubic-upscaled input's Qwen-Image VAE latent and its DINOv2-L features. These folders hold its four graphs for 512 x 512 tiles: `image_encoder` (DINOv2-L, layer 17), `vae_encoder`, `transformer` (the one flow step) and `vae_decoder`. The tiling and VOSR's wavelet colour fix run outside the graphs, as below. **Run it** (ONNX Runtime; a picture is upscaled 4x with bicubic, cut into 512 px tiles with 64 px overlap, restored tile by tile and blended, then colour-fixed against the bicubic picture): ```python import cv2, numpy as np, onnxruntime as ort from PIL import Image d, prov = "int8", ["CUDAExecutionProvider", "CPUExecutionProvider"] g = {p: ort.InferenceSession(f"{d}/{p}/model.onnx", providers=prov) for p in ("image_encoder", "vae_encoder", "transformer", "vae_decoder")} rng = np.random.default_rng(42) def tile(x): # x: [1, 3, 512, 512] in -1..1 tok = g["image_encoder"].run(None, {"lq": x})[0] lat = g["vae_encoder"].run(None, {"lq": x})[0] z = g["transformer"].run(None, {"lq_latent": lat, "noise": rng.standard_normal(lat.shape, np.float32), "tokens": tok})[0] return g["vae_decoder"].run(None, {"latent": z})[0][0] lr = Image.open("photo.png").convert("RGB") up = lr.resize((lr.width * 4, lr.height * 4), Image.BICUBIC) x = np.asarray(up, np.float32).transpose(2, 0, 1) / 127.5 - 1 H, W = x.shape[1:] x = np.pad(x, ((0, 0), (0, max(512 - H, 0)), (0, max(512 - W, 0))), mode="reflect") Hp, Wp = x.shape[1:] pos = lambda n: sorted({*range(0, max(n - 512, 0) + 1, 448), max(n - 512, 0)}) ramp = np.minimum(np.arange(512) + 1, 64) / 64; w2 = np.outer(np.minimum(ramp, ramp[::-1]), np.minimum(ramp, ramp[::-1])) acc, wsum = np.zeros_like(x), np.zeros((Hp, Wp)) for y0 in pos(Hp): for x0 in pos(Wp): acc[:, y0:y0 + 512, x0:x0 + 512] += tile(x[None, :, y0:y0 + 512, x0:x0 + 512].copy()) * w2 wsum[y0:y0 + 512, x0:x0 + 512] += w2 sr = ((acc / wsum)[:, :H, :W].transpose(1, 2, 0) + 1) / 2 src = np.asarray(up, np.float32) / 255 # wavelet colour fix (VOSR's default) sr = np.clip(cv2.GaussianBlur(src, (0, 0), 5) + sr - cv2.GaussianBlur(sr.astype(np.float32), (0, 0), 5), 0, 1) Image.fromarray((sr * 255).astype(np.uint8)).save("photo_x4.png") ``` The original tiles in latent space and blends latents; tiling in pixels as above is simpler, but on pictures larger than one tile it is not identical to the PyTorch pipeline. **Precisions.** int8: the transformer's weights int8 per output channel (weight-only), other graphs as in fp16. int4: the transformer's MatMul weights 4-bit (MatMulNBits, block 32) and its other weights int8, other graphs as in fp16. No fp16 or bf16 transformer: converting the 5.6 GB fp32 graph needed more memory than our build machine has, and VOSR's code mixes fp32 and fp16 tensors when exported in half precision. The example above uses `int8`. **Benchmark.** Set14 and BSD100 at 4x (bicubic-downscaled inputs), the pipeline above on an RTX 3080 Laptop GPU with ONNX Runtime 1.30: each precision's PSNR against the fp32 pipeline's output (same noise), and PSNR / SSIM (Y channel, 4 px border cropped) against the ground truth. VOSR is a generative model trained for real-world degradations: it adds plausible detail, which PSNR penalizes, so compare precisions with each other rather than with PSNR-oriented upscalers. | Pipeline | Size | vs fp32 PSNR (Set14 / BSD100) | PSNR-Y / SSIM-Y Set14 | PSNR-Y / SSIM-Y BSD100 | Time / picture | Peak VRAM | |---|---|---|---|---|---|---| | fp32 (reference, not published) | 6.68 GB | - | 25.82 / 0.698 | 24.96 / 0.655 | 0.61 s | 10.5 GB | | int8 | 1.96 GB | 36.7 / 35.1 dB | 25.82 / 0.698 | 24.95 / 0.655 | 0.52 s | 5.5 GB | | int4 | 1.46 GB | 30.6 / 30.1 dB | 25.57 / 0.690 | 24.79 / 0.646 | 0.54 s | 4.5 GB | ## How these were made From [VOSR 2.0](https://github.com/cswry/VOSR) at revision `516f292b99`: each part exported with `torch.onnx`, then converted or quantized with ONNX Runtime's tools (fp16 / bf16 casts, int8 and int4 weight quantization). Every graph was checked against the original before upload; the `sha256` column above is what the files must hash to. ## License Apache-2.0. These files are a derivative of the original model and carry its license: it is copied in this repository, and it governs your use of these files. The original model card follows unchanged. --- # Original model card
A framework for native generative image restoration.
#### 🚩 Accepted by CVPR 2026 [](https://arxiv.org/pdf/2604.03225) [](https://modelscope.cn/models/LULALULALU/VOSR_CKPT) [](https://huggingface.co/CSWRY/VOSR) [](https://modelscope.cn/datasets/LULALULALU/ScreenSR) [](https://huggingface.co/datasets/CSWRY/ScreenSR) [Rongyuan Wu](https://scholar.google.com/citations?user=A-U8zE8AAAAJ&hl=zh-CN)1,2,* | [Lingchen Sun](https://scholar.google.com/citations?user=ZCDjTn8AAAAJ&hl=zh-CN)1,2,* | [Zhengqiang Zhang](https://scholar.google.com/citations?user=UX26wSMAAAAJ&hl=en)1,2 | [Xiangtao Kong](https://scholar.google.com/citations?user=lueNzSgAAAAJ&hl=zh-CN)1,2
Overview of the VOSR framework, including the overall pipeline and our condition / guidance design.
## 📌 Quick Links - [📰 News](#news) - [🧰 Preparation](#preparation) - [🏋️ Training](#training) - [🔍 Inference](#inference) - [📮 Contact](#contact) - [📚 Citation](#citation) ## 📰 News - 2026.08.22 **VOSR 2.0** released: a one-step 1.4B DiT, vision-only model with improved fine-structure restoration. See [visual comparison](https://cswry.github.io/vosr2/). Thanks to [ylchen333](https://github.com/ylchen333) for bringing VOSR to ComfyUI with [ComfyUI-VOSR2](https://github.com/ylchen333/ComfyUI-VOSR2). - 2026.04.10 Public release: training and inference code, [pretrained checkpoints](https://modelscope.cn/models/LULALULALU/VOSR_CKPT), bundled VAE / decoder assets, and the [ScreenSR](https://modelscope.cn/datasets/LULALULALU/ScreenSR) benchmark. Setup and file layout: [Preparation](#preparation); commands: [Training](#training) and [Inference](#inference). ---
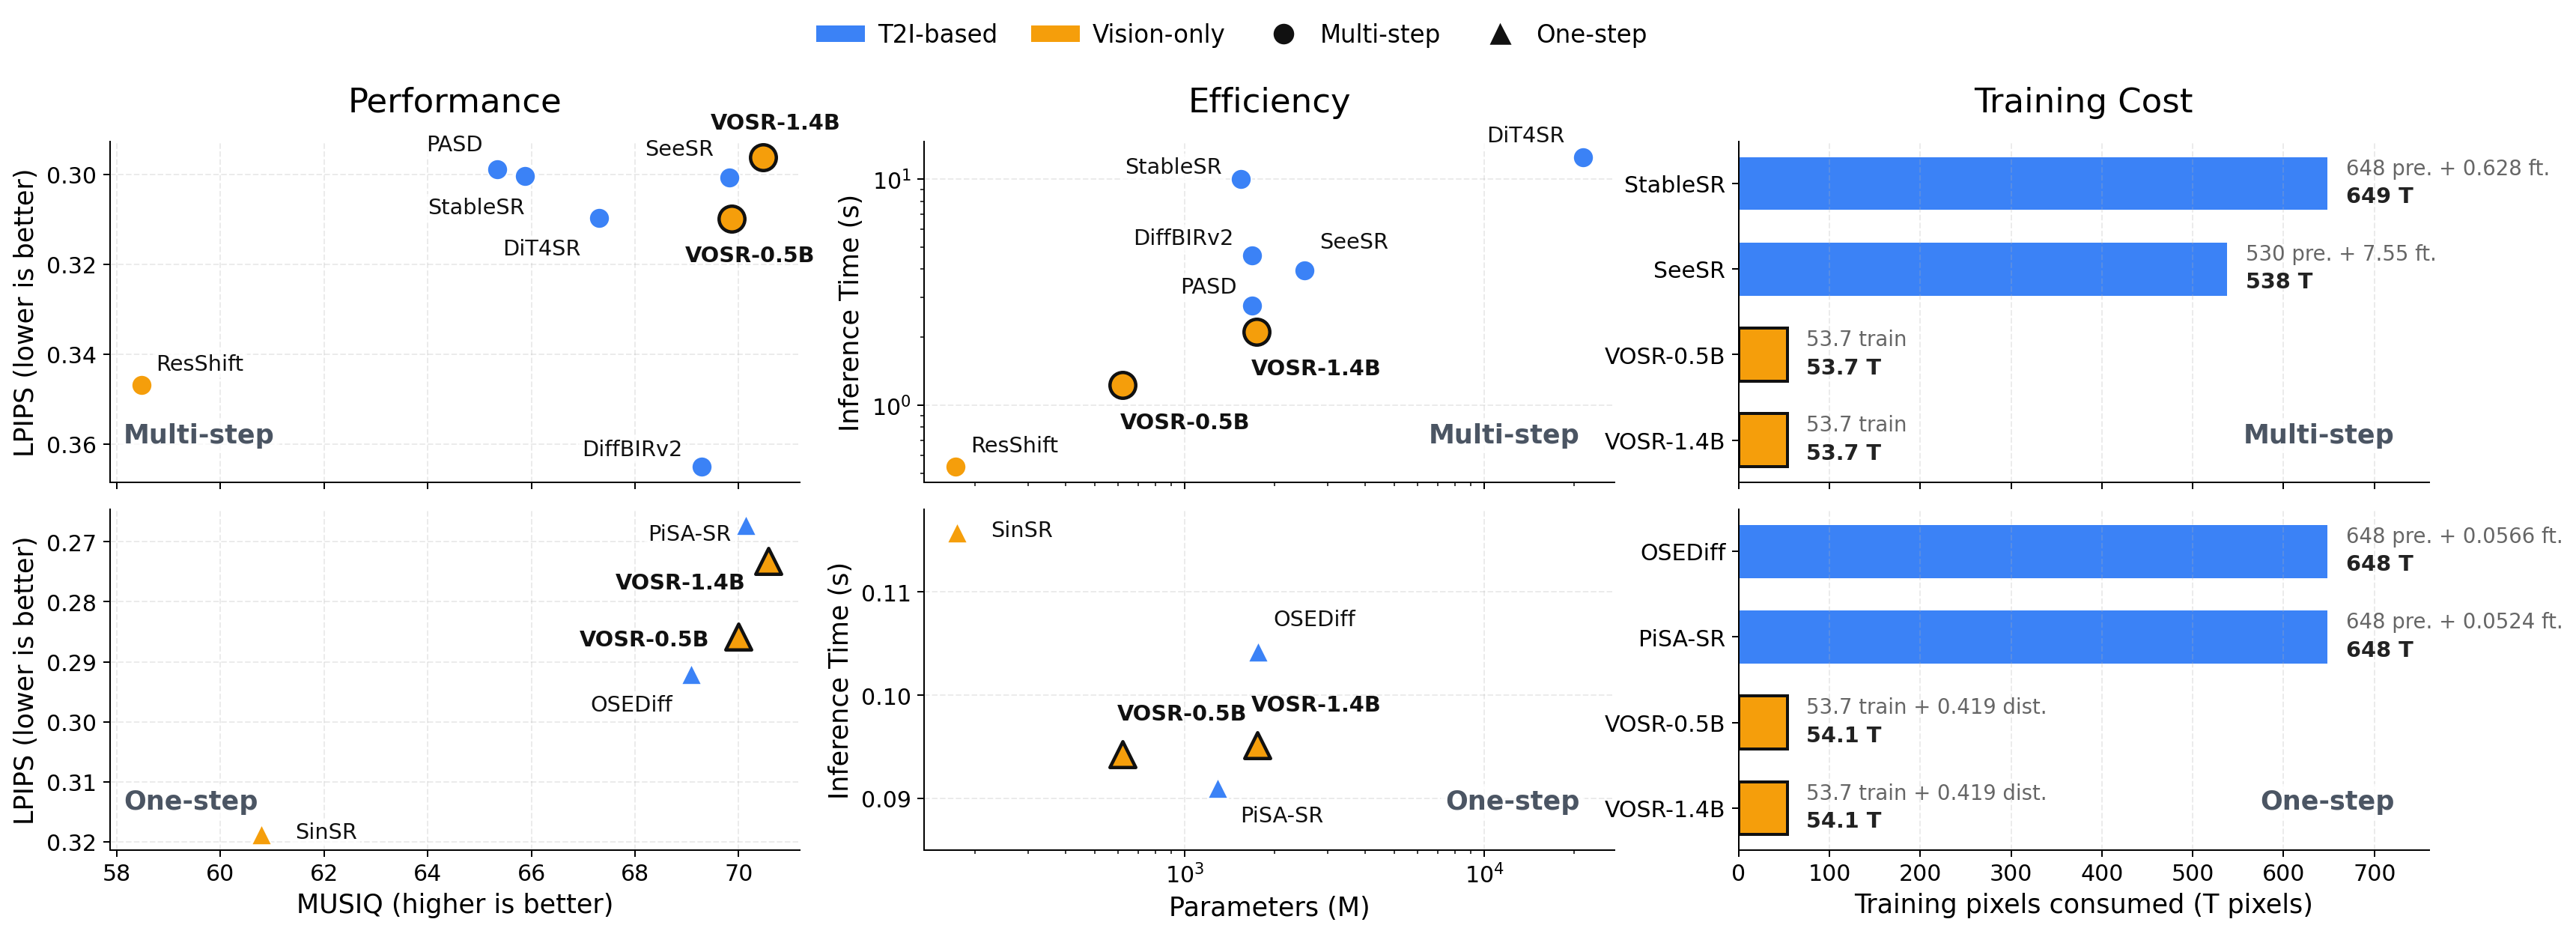
Comparison with prior methods in performance, inference efficiency, and training cost.
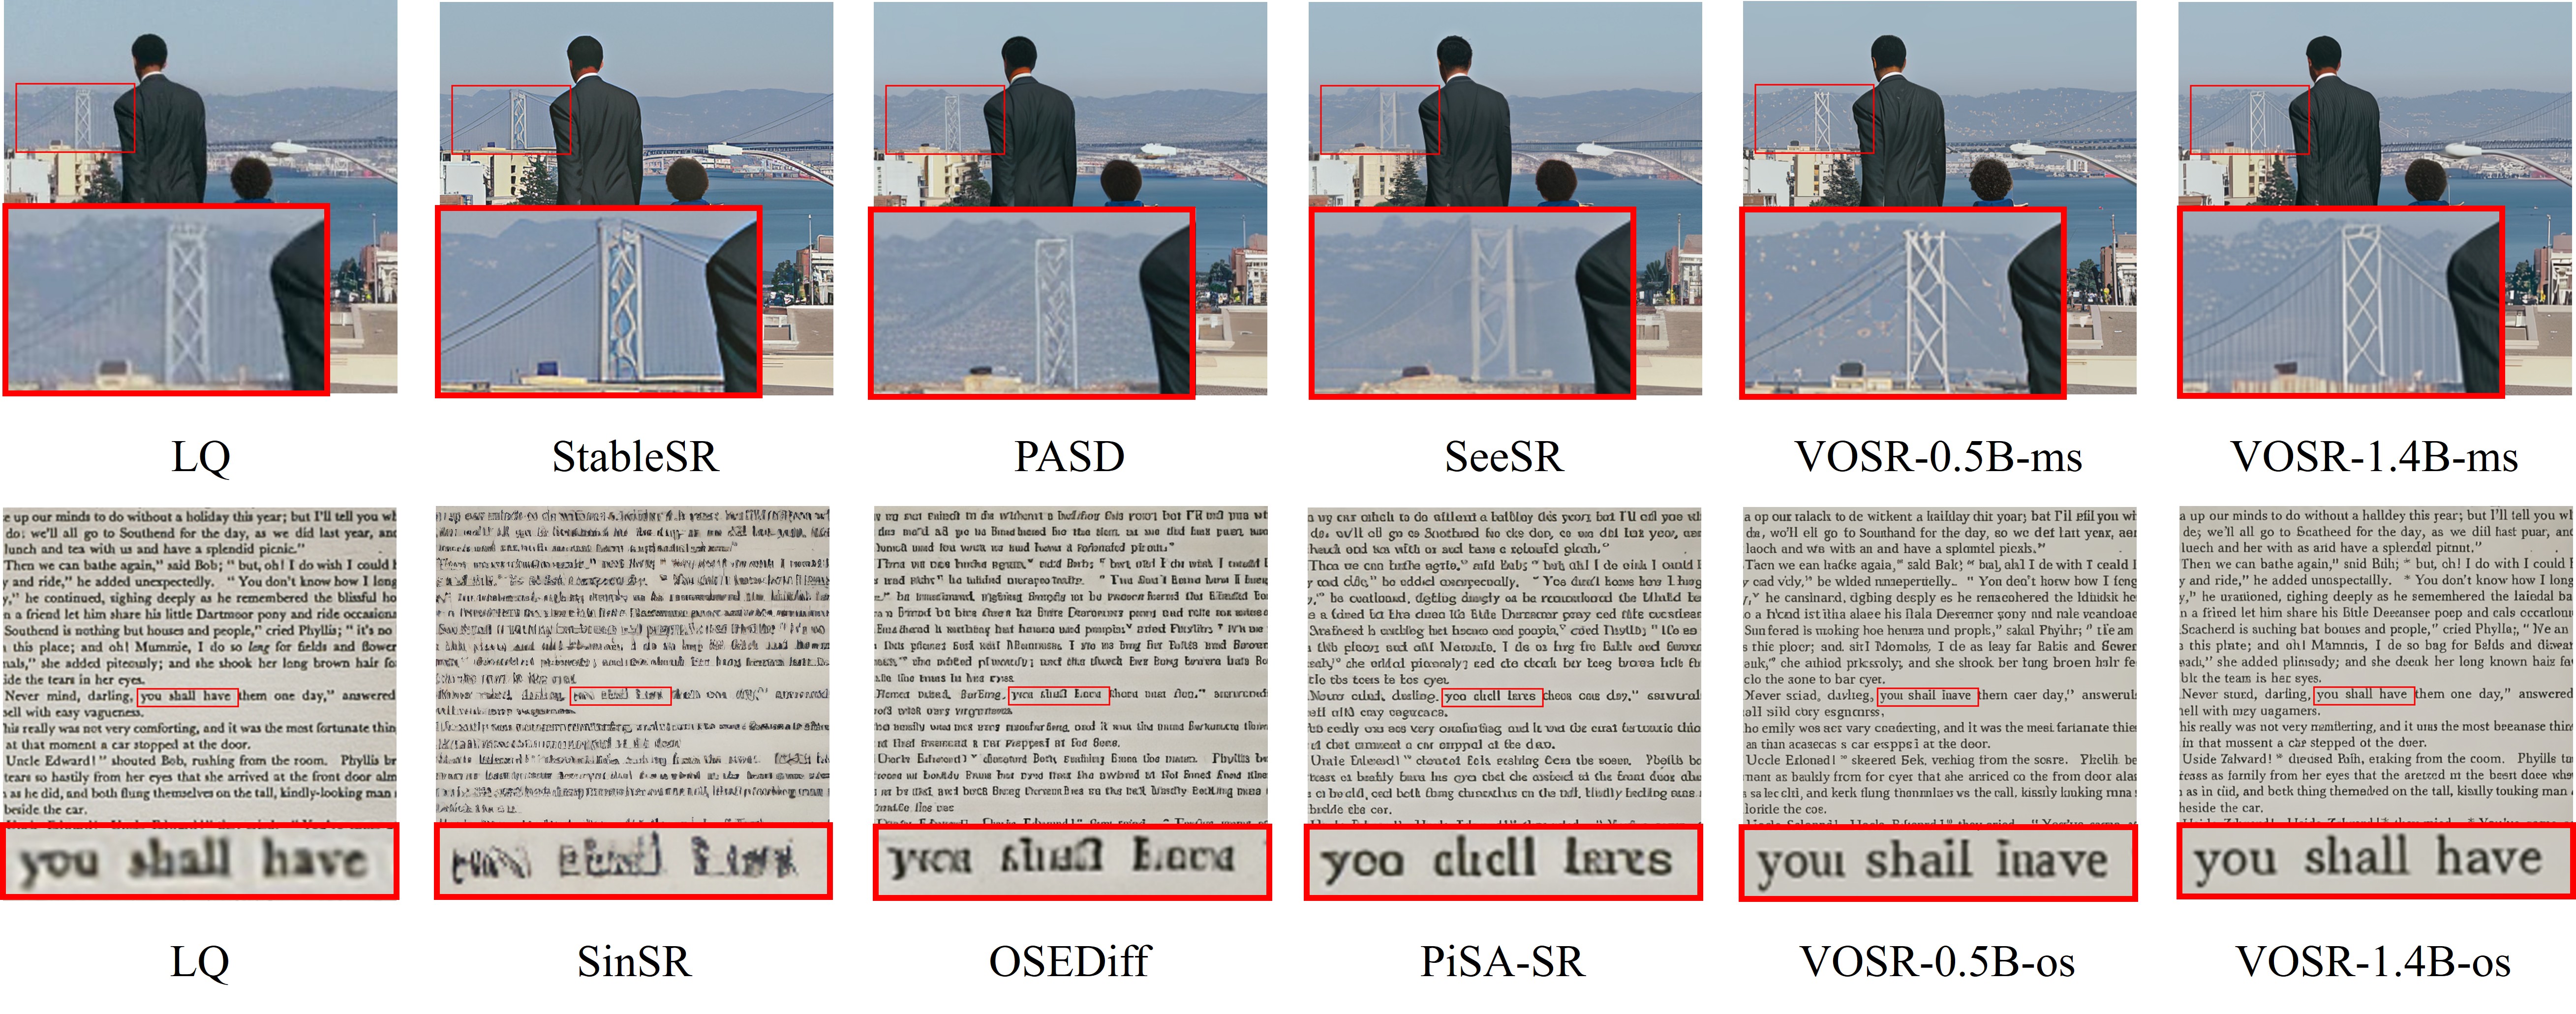
VOSR better preserves fine structures and text readability.
## 🧰 Preparation ### Dependencies and Installation ```bash ## clone this repository git clone https://github.com/cswry/VOSR.git cd VOSR # create an environment with python >= 3.8 conda create -n vosr python=3.8 conda activate vosr pip install -r requirements.txt ``` ### 📦 Model Weights Download all pretrained weights from [ModelScope](https://modelscope.cn/models/LULALULALU/VOSR_CKPT) or [Hugging Face](https://huggingface.co/CSWRY/VOSR), and place them under `preset/ckpts/`. The expected structure: ```text preset/ckpts/ |-- Qwen-Image-vae-2d/ # Qwen-Image VAE (2D, for 1.4B models) |-- stable-diffusion-2-1-base/ # SD2.1 VAE (for 0.5B models) |-- sd21_lwdecoder.pth # Lightweight decoder for SD2.1 VAE |-- torch_cache/ # DINOv2 pretrained weights |-- VOSR2/ # VOSR 2.0 one-step (1.4B) model |-- VOSR_0.5B_ms/ # 0.5B multi-step model |-- VOSR_0.5B_os/ # 0.5B one-step (distilled) model |-- VOSR_1.4B_ms/ # 1.4B multi-step model `-- VOSR_1.4B_os/ # 1.4B one-step (distilled) model ``` #### VAE and decoder For `VOSR-0.5B`, we provide `sd21_lwdecoder.pth`, a lightweight replacement for the original SD2.1 VAE decoder. It achieves comparable overall visual quality in our evaluation, while performing slightly better on text-rich and document-like images. When scaling to `VOSR-1.4B`, we adopt the 16-channel Qwen-Image VAE to better preserve input fidelity. Although Qwen-Image is designed for T2I generation, it is released in a video-VAE form, which is unnecessarily slow for image SR inference. We therefore provide `Qwen-Image-vae-2d`, an image-only 2D variant extracted from the original model to remove the overhead of the full 3D design. ### 🗂️ Training Data We support two data loading modes, configured via `dataset_type` in the YAML config: - `txt` - Each folder contains individual image files. A txt config lists folders with sampling weights. - `webdataset` - Each folder contains `.tar` shards. Same txt config format, loaded via WebDataset. Create a dataset config file (e.g., `configs/train_txt/train_dataset_txt.txt`): ```text /path/to/dataset_A, 2 /path/to/dataset_B, 1 /path/to/dataset_C, 1 ``` Each line: `
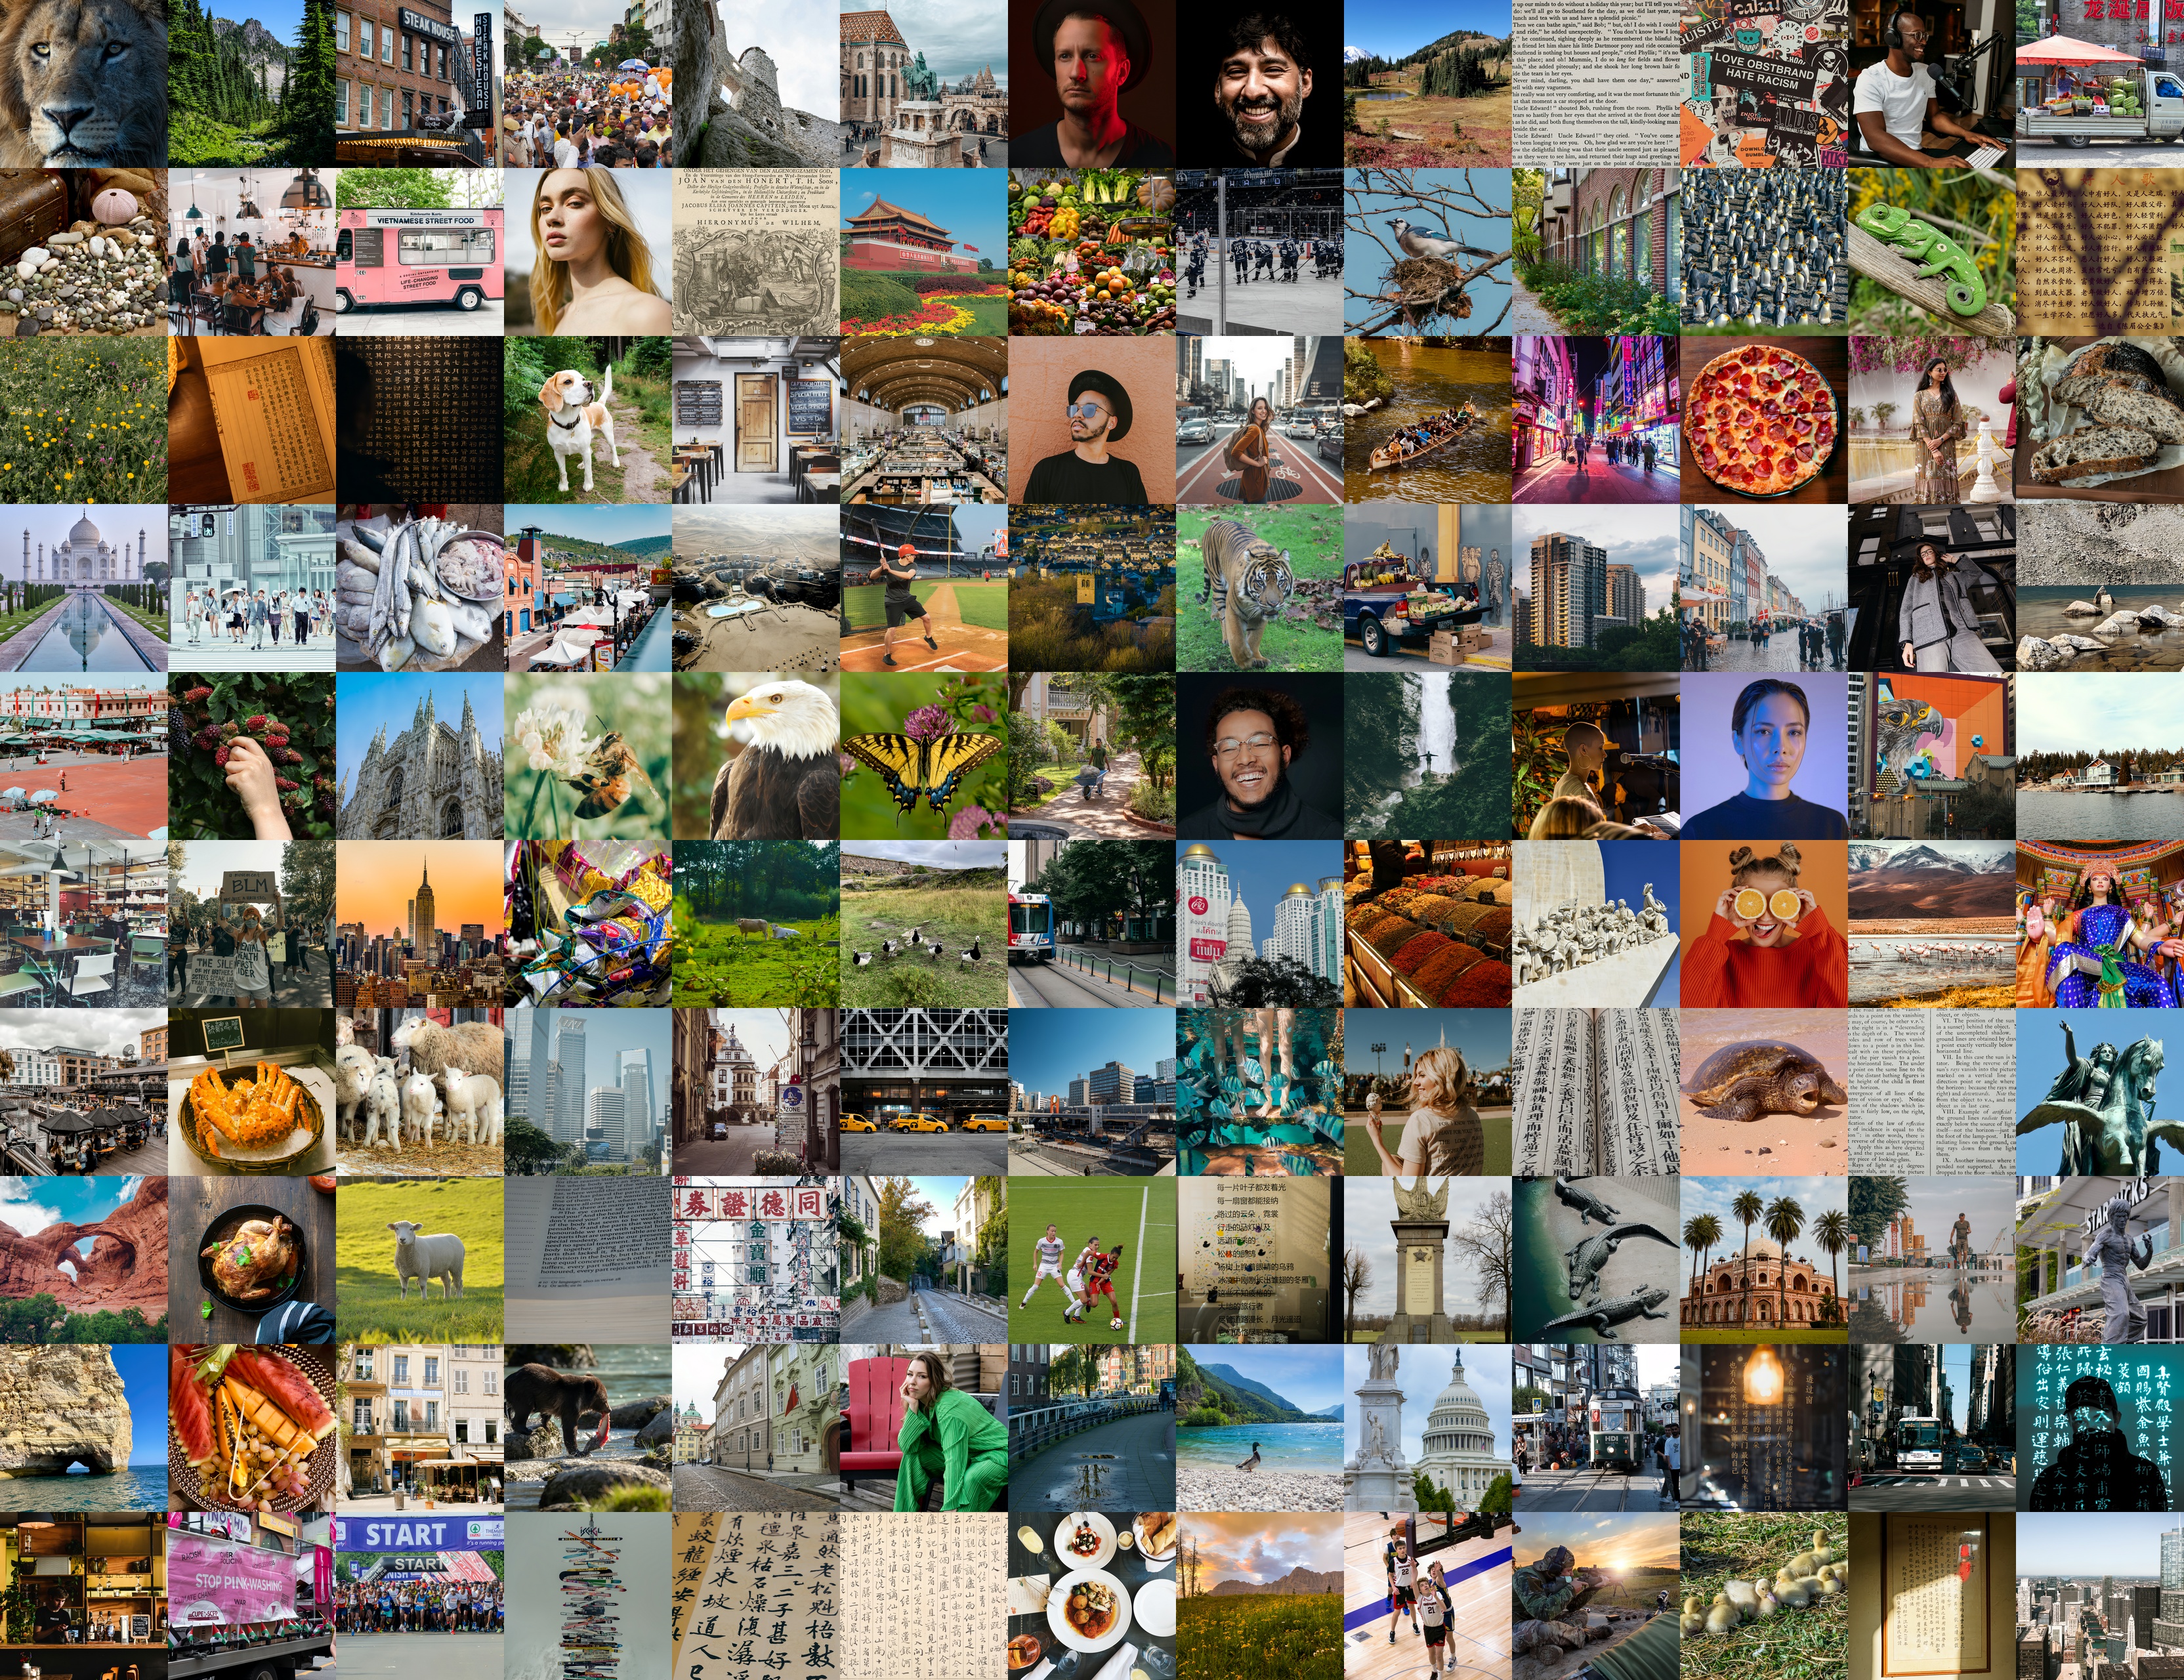
Thumbnail montage of the ScreenSR benchmark, covering diverse scenes, subjects, and multilingual text.
--- ## 🏋️ Training The provided training configs disable experiment tracking by default (`report_to: none`). To enable Weights & Biases logging, run `wandb login` with your own account and set `report_to: wandb` in the YAML config. ### Multi-step Training ```bash # VOSR-0.5B torchrun --nproc_per_node=8 train_vosr.py --config configs/train_yml/multi_step/VOSR_0.5B.yml # VOSR-1.4B torchrun --nproc_per_node=8 train_vosr.py --config configs/train_yml/multi_step/VOSR_1.4B.yml ``` ### One-step Distillation Requires a trained multi-step teacher checkpoint. Set `teacher_ckpt` and `pretrained_ckpt` in the YAML config. ```bash # VOSR-0.5B one-step torchrun --nproc_per_node=8 train_vosr_distill.py --config configs/train_yml/one_step/VOSR_0.5B.yml # VOSR-1.4B one-step torchrun --nproc_per_node=8 train_vosr_distill.py --config configs/train_yml/one_step/VOSR_1.4B.yml ``` --- ## 🔍 Inference Single-GPU inference. ### VOSR 2.0 one-step (default) VOSR 2.0 is the default one-step model (1.4B DiT, vision-only, with improved fine-structure restoration). ```bash # VOSR2-1.4B one-step python inference_vosr_onestep.py \ -c preset/ckpts/VOSR2 \ -i preset/datasets/inp_data \ -o preset/results \ -u 4 ``` ### Multi-step models Multi-step sampling defaults to **25 steps** (`--infer_steps`, default 25). Override if you need fewer or more function evaluations. Two knobs mainly affect the trade-off between faithfulness to the LR input and generative detail (both can be set via CLI to override `args.json`): - `--cfg_scale` - Higher values tend to emphasize fidelity to the condition; lower values give more generative freedom. The sweet spot depends on input degradation strength. In our experiments, roughly `-0.5` to `2` is a usable range; `0.5` is a practical default. - `--weak_cond_strength_aelq` - During training this is sampled uniformly in `[0.05, 0.25]` so the checkpoint supports a wide range at inference via the same flag (smaller -> more generative, larger -> more faithful). Default `0.1`. Benchmark presets (multi-step): for apples-to-apples evaluation we use `--cfg_scale -0.5` on RealSR and `--cfg_scale 0.5` on [ScreenSR](https://modelscope.cn/datasets/LULALULALU/ScreenSR). ```bash # Inputs under preset/datasets/inp_data follow RealSR-style evaluation; use --cfg_scale -0.5 (see benchmark presets above). # VOSR-0.5B multi-step (25 steps) python inference_vosr.py \ -c preset/ckpts/VOSR_0.5B_ms \ -i preset/datasets/inp_data \ -o preset/results \ -u 4 # VOSR-1.4B multi-step (25 steps) python inference_vosr.py \ -c preset/ckpts/VOSR_1.4B_ms \ -i preset/datasets/inp_data \ -o preset/results \ -u 4 ``` ### One-step models One-step models use `--infer_steps` with default `1` (typical for distilled checkpoints). ```bash # VOSR-0.5B one-step python inference_vosr_onestep.py \ -c preset/ckpts/VOSR_0.5B_os \ -i preset/datasets/inp_data \ -o preset/results \ -u 4 # VOSR-1.4B one-step python inference_vosr_onestep.py \ -c preset/ckpts/VOSR_1.4B_os \ -i preset/datasets/inp_data \ -o preset/results \ -u 4 ``` ### Common arguments `-c` checkpoint path, `-i` input image or folder, `-o` output directory, `-u` upscale factor. Outputs are saved as **PNG directly into the `-o` folder**; color alignment defaults to `wavelet` (`--align_method wavelet|adain|nofix`). - Multi-step (`inference_vosr.py`): `--infer_steps` (default `25`), `--cfg_scale`, `--weak_cond_strength_aelq` (see above). - One-step (`inference_vosr_onestep.py`): `--infer_steps` (default `1`). - Both: `--posterior_mode` / `--no-posterior_mode` — deterministic VAE latent (`latent_dist.mode()`) is the default, for reproducible results and seam-free tiled inference. ### Tiled inference for large images Large images are tiled in latent space to bound GPU memory: - `--tile_size 512` — DiT tile size in pixels (default `0` = disabled). Use for large images; overlapping tiles are Gaussian-blended. - `--vae_tile_size 1024` — VAE encoder/decoder tile size in pixels (default `0` = full-image VAE). The Qwen VAE attention is O(N)-memory, so full-image encode/decode already fits up to ~8K inputs; VAE tiling is only needed for extreme sizes. - `--vae_tile_overlap` — VAE tile overlap (default: follows `--tile_overlap`). ```bash # VOSR-1.4B one-step on a large image with DiT + VAE tiling python inference_vosr_onestep.py \ -c preset/ckpts/VOSR_1.4B_os \ -i large_input.png \ -o preset/results \ -u 4 --tile_size 512 --vae_tile_size 1024 ``` --- ## 📮 Contact If you have any questions, please feel free to contact: `rong-yuan.wu@connect.polyu.hk` ## 📚 Citation If VOSR is useful for your research, please consider citing: ```bibtex @inproceedings{wu2026vosr, title = {VOSR: A Vision-Only Generative Model for Image Super-Resolution}, author = {Wu, Rongyuan and Sun, Lingchen and Zhang, Zhengqiang and Kong, Xiangtao and Zhao, Jixin and Wang, Shihao and Zhang, Lei}, booktitle = {Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition}, year = {2026} } ``` ## Acknowledgements This project benefits from [stable-diffusion-2-1-base](https://huggingface.co/Manojb/stable-diffusion-2-1-base), [LightningDiT](https://github.com/hustvl/LightningDiT), [Qwen-Image](https://huggingface.co/Qwen/Qwen-Image), [DINOv2](https://github.com/facebookresearch/dinov2), [BasicSR](https://github.com/XPixelGroup/BasicSR), [Real-ESRGAN](https://github.com/xinntao/Real-ESRGAN), [RCGM](https://github.com/LINs-lab/RCGM), and [Shortcut-models](https://github.com/kvfrans/shortcut-models). We thank the authors for their open-source contributions. ## ⚖️ License This project is released under the Apache License 2.0 unless otherwise noted. See [LICENSE](https://raw.githubusercontent.com/cswry/VOSR/516f292b99cf23c76fdc33351e86dc4f97711fe8/LICENSE) for details. Downloadable model weights, benchmark data, and external assets may have separate terms on their hosting pages.