epochs
+ print(f"saving the model at the end of epoch {epoch}, iters {total_iters}")
+ model.save_networks("latest")
+ model.save_networks(epoch)
+
+ print(f"End of epoch {epoch} / {opt.n_epochs + opt.n_epochs_decay} \t Time Taken: {time.time() - epoch_start_time:.0f} sec")
+
+ cleanup_ddp()
diff --git a/pix2pix_vgg/.replit b/pix2pix_vgg/.replit
new file mode 100644
index 0000000000000000000000000000000000000000..94513bcb6de8effa36d8335fba26ff7b3d11a703
--- /dev/null
+++ b/pix2pix_vgg/.replit
@@ -0,0 +1,2 @@
+language = "python3"
+run = " [Tensorflow] (by Christopher Hesse), [Tensorflow] (by Eyyüb Sariu), [Tensorflow (face2face)] (by Dat Tran), [Tensorflow (film)] (by Arthur Juliani), [Tensorflow (zi2zi)] (by Yuchen Tian), [Chainer] (by mattya), [tf/torch/keras/lasagne] (by tjwei), [Pytorch] (by taey16)
"
\ No newline at end of file
diff --git a/pix2pix_vgg/.vscode/sftp.json b/pix2pix_vgg/.vscode/sftp.json
new file mode 100644
index 0000000000000000000000000000000000000000..132e1745bb6809386ac9398ab030ba8fce5e85e9
--- /dev/null
+++ b/pix2pix_vgg/.vscode/sftp.json
@@ -0,0 +1,13 @@
+{
+ "host": "192.168.1.214",
+ "username": "liutao",
+ "password": "LT*7^5@1",
+ "remotePath": "/data1/liutao/pix2pix",
+ "uploadOnSave": true,
+ "downloadOnOpen": true,
+ "ignore": [
+ "**/.vscode/**",
+ "**/.git/**",
+ "**/node_modules/**"
+ ]
+}
diff --git a/pix2pix_vgg/CycleGAN.ipynb b/pix2pix_vgg/CycleGAN.ipynb
new file mode 100644
index 0000000000000000000000000000000000000000..99df56ac5ed8348393207e33a490e8c450d72498
--- /dev/null
+++ b/pix2pix_vgg/CycleGAN.ipynb
@@ -0,0 +1,273 @@
+{
+ "cells": [
+ {
+ "cell_type": "markdown",
+ "metadata": {
+ "colab_type": "text",
+ "id": "view-in-github"
+ },
+ "source": [
+ " "
+ ]
+ },
+ {
+ "cell_type": "markdown",
+ "metadata": {
+ "colab_type": "text",
+ "id": "5VIGyIus8Vr7"
+ },
+ "source": [
+ "Take a look at the [repository](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix) for more information"
+ ]
+ },
+ {
+ "cell_type": "markdown",
+ "metadata": {
+ "colab_type": "text",
+ "id": "7wNjDKdQy35h"
+ },
+ "source": [
+ "# Install"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": null,
+ "metadata": {
+ "colab": {},
+ "colab_type": "code",
+ "id": "TRm-USlsHgEV"
+ },
+ "outputs": [],
+ "source": [
+ "!git clone https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": null,
+ "metadata": {
+ "colab": {},
+ "colab_type": "code",
+ "id": "Pt3igws3eiVp"
+ },
+ "outputs": [],
+ "source": [
+ "import os\n",
+ "os.chdir('pytorch-CycleGAN-and-pix2pix/')"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": null,
+ "metadata": {
+ "colab": {},
+ "colab_type": "code",
+ "id": "z1EySlOXwwoa"
+ },
+ "outputs": [],
+ "source": [
+ "!pip install -r requirements.txt"
+ ]
+ },
+ {
+ "cell_type": "markdown",
+ "metadata": {
+ "colab_type": "text",
+ "id": "8daqlgVhw29P"
+ },
+ "source": [
+ "# Datasets\n",
+ "\n",
+ "Download one of the official datasets with:\n",
+ "\n",
+ "- `bash ./datasets/download_cyclegan_dataset.sh [apple2orange, summer2winter_yosemite, horse2zebra, monet2photo, cezanne2photo, ukiyoe2photo, vangogh2photo, maps, cityscapes, facades, iphone2dslr_flower, ae_photos]`\n",
+ "\n",
+ "Or use your own dataset by creating the appropriate folders and adding in the images.\n",
+ "\n",
+ "- Create a dataset folder under `/dataset` for your dataset.\n",
+ "- Create subfolders `testA`, `testB`, `trainA`, and `trainB` under your dataset's folder. Place any images you want to transform from a to b (cat2dog) in the `testA` folder, images you want to transform from b to a (dog2cat) in the `testB` folder, and do the same for the `trainA` and `trainB` folders."
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": null,
+ "metadata": {
+ "colab": {},
+ "colab_type": "code",
+ "id": "vrdOettJxaCc"
+ },
+ "outputs": [],
+ "source": [
+ "!bash ./datasets/download_cyclegan_dataset.sh horse2zebra"
+ ]
+ },
+ {
+ "cell_type": "markdown",
+ "metadata": {
+ "colab_type": "text",
+ "id": "gdUz4116xhpm"
+ },
+ "source": [
+ "# Pretrained models\n",
+ "\n",
+ "Download one of the official pretrained models with:\n",
+ "\n",
+ "- `bash ./scripts/download_cyclegan_model.sh [apple2orange, orange2apple, summer2winter_yosemite, winter2summer_yosemite, horse2zebra, zebra2horse, monet2photo, style_monet, style_cezanne, style_ukiyoe, style_vangogh, sat2map, map2sat, cityscapes_photo2label, cityscapes_label2photo, facades_photo2label, facades_label2photo, iphone2dslr_flower]`\n",
+ "\n",
+ "Or add your own pretrained model to `./checkpoints/{NAME}_pretrained/latest_net_G.pt`"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": null,
+ "metadata": {
+ "colab": {},
+ "colab_type": "code",
+ "id": "B75UqtKhxznS"
+ },
+ "outputs": [],
+ "source": [
+ "!bash ./scripts/download_cyclegan_model.sh horse2zebra"
+ ]
+ },
+ {
+ "cell_type": "markdown",
+ "metadata": {
+ "colab_type": "text",
+ "id": "yFw1kDQBx3LN"
+ },
+ "source": [
+ "# Training\n",
+ "\n",
+ "- `python train.py --dataroot ./datasets/horse2zebra --name horse2zebra --model cycle_gan`\n",
+ "\n",
+ "Change the `--dataroot` and `--name` to your own dataset's path and model's name. Use `--gpu_ids 0,1,..` to train on multiple GPUs and `--batch_size` to change the batch size. I've found that a batch size of 16 fits onto 4 V100s and can finish training an epoch in ~90s.\n",
+ "\n",
+ "Once your model has trained, copy over the last checkpoint to a format that the testing model can automatically detect:\n",
+ "\n",
+ "Use `cp ./checkpoints/horse2zebra/latest_net_G_A.pth ./checkpoints/horse2zebra/latest_net_G.pth` if you want to transform images from class A to class B and `cp ./checkpoints/horse2zebra/latest_net_G_B.pth ./checkpoints/horse2zebra/latest_net_G.pth` if you want to transform images from class B to class A.\n"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": null,
+ "metadata": {
+ "colab": {},
+ "colab_type": "code",
+ "id": "0sp7TCT2x9dB"
+ },
+ "outputs": [],
+ "source": [
+ "!python train.py --dataroot ./datasets/horse2zebra --name horse2zebra --model cycle_gan --display_id -1"
+ ]
+ },
+ {
+ "cell_type": "markdown",
+ "metadata": {
+ "colab_type": "text",
+ "id": "9UkcaFZiyASl"
+ },
+ "source": [
+ "# Testing\n",
+ "\n",
+ "- `python test.py --dataroot datasets/horse2zebra/testA --name horse2zebra_pretrained --model test --no_dropout`\n",
+ "\n",
+ "Change the `--dataroot` and `--name` to be consistent with your trained model's configuration.\n",
+ "\n",
+ "> from https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix:\n",
+ "> The option --model test is used for generating results of CycleGAN only for one side. This option will automatically set --dataset_mode single, which only loads the images from one set. On the contrary, using --model cycle_gan requires loading and generating results in both directions, which is sometimes unnecessary. The results will be saved at ./results/. Use --results_dir {directory_path_to_save_result} to specify the results directory.\n",
+ "\n",
+ "> For your own experiments, you might want to specify --netG, --norm, --no_dropout to match the generator architecture of the trained model."
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": null,
+ "metadata": {
+ "colab": {},
+ "colab_type": "code",
+ "id": "uCsKkEq0yGh0"
+ },
+ "outputs": [],
+ "source": [
+ "!python test.py --dataroot datasets/horse2zebra/testA --name horse2zebra_pretrained --model test --no_dropout"
+ ]
+ },
+ {
+ "cell_type": "markdown",
+ "metadata": {
+ "colab_type": "text",
+ "id": "OzSKIPUByfiN"
+ },
+ "source": [
+ "# Visualize"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": null,
+ "metadata": {
+ "colab": {},
+ "colab_type": "code",
+ "id": "9Mgg8raPyizq"
+ },
+ "outputs": [],
+ "source": [
+ "import matplotlib.pyplot as plt\n",
+ "\n",
+ "img = plt.imread('./results/horse2zebra_pretrained/test_latest/images/n02381460_1010_fake.png')\n",
+ "plt.imshow(img)"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": null,
+ "metadata": {
+ "colab": {},
+ "colab_type": "code",
+ "id": "0G3oVH9DyqLQ"
+ },
+ "outputs": [],
+ "source": [
+ "import matplotlib.pyplot as plt\n",
+ "\n",
+ "img = plt.imread('./results/horse2zebra_pretrained/test_latest/images/n02381460_1010_real.png')\n",
+ "plt.imshow(img)"
+ ]
+ }
+ ],
+ "metadata": {
+ "accelerator": "GPU",
+ "colab": {
+ "collapsed_sections": [],
+ "include_colab_link": true,
+ "name": "CycleGAN",
+ "provenance": []
+ },
+ "environment": {
+ "name": "tf2-gpu.2-3.m74",
+ "type": "gcloud",
+ "uri": "gcr.io/deeplearning-platform-release/tf2-gpu.2-3:m74"
+ },
+ "kernelspec": {
+ "display_name": "Python 3",
+ "language": "python",
+ "name": "python3"
+ },
+ "language_info": {
+ "codemirror_mode": {
+ "name": "ipython",
+ "version": 3
+ },
+ "file_extension": ".py",
+ "mimetype": "text/x-python",
+ "name": "python",
+ "nbconvert_exporter": "python",
+ "pygments_lexer": "ipython3",
+ "version": "3.7.10"
+ }
+ },
+ "nbformat": 4,
+ "nbformat_minor": 4
+}
diff --git a/pix2pix_vgg/LICENSE b/pix2pix_vgg/LICENSE
new file mode 100644
index 0000000000000000000000000000000000000000..d75f0ee8466f00cf04da906a6fca115c7910399f
--- /dev/null
+++ b/pix2pix_vgg/LICENSE
@@ -0,0 +1,58 @@
+Copyright (c) 2017, Jun-Yan Zhu and Taesung Park
+All rights reserved.
+
+Redistribution and use in source and binary forms, with or without
+modification, are permitted provided that the following conditions are met:
+
+* Redistributions of source code must retain the above copyright notice, this
+ list of conditions and the following disclaimer.
+
+* Redistributions in binary form must reproduce the above copyright notice,
+ this list of conditions and the following disclaimer in the documentation
+ and/or other materials provided with the distribution.
+
+THIS SOFTWARE IS PROVIDED BY THE COPYRIGHT HOLDERS AND CONTRIBUTORS "AS IS"
+AND ANY EXPRESS OR IMPLIED WARRANTIES, INCLUDING, BUT NOT LIMITED TO, THE
+IMPLIED WARRANTIES OF MERCHANTABILITY AND FITNESS FOR A PARTICULAR PURPOSE ARE
+DISCLAIMED. IN NO EVENT SHALL THE COPYRIGHT HOLDER OR CONTRIBUTORS BE LIABLE
+FOR ANY DIRECT, INDIRECT, INCIDENTAL, SPECIAL, EXEMPLARY, OR CONSEQUENTIAL
+DAMAGES (INCLUDING, BUT NOT LIMITED TO, PROCUREMENT OF SUBSTITUTE GOODS OR
+SERVICES; LOSS OF USE, DATA, OR PROFITS; OR BUSINESS INTERRUPTION) HOWEVER
+CAUSED AND ON ANY THEORY OF LIABILITY, WHETHER IN CONTRACT, STRICT LIABILITY,
+OR TORT (INCLUDING NEGLIGENCE OR OTHERWISE) ARISING IN ANY WAY OUT OF THE USE
+OF THIS SOFTWARE, EVEN IF ADVISED OF THE POSSIBILITY OF SUCH DAMAGE.
+
+
+--------------------------- LICENSE FOR pix2pix --------------------------------
+BSD License
+
+For pix2pix software
+Copyright (c) 2016, Phillip Isola and Jun-Yan Zhu
+All rights reserved.
+
+Redistribution and use in source and binary forms, with or without
+modification, are permitted provided that the following conditions are met:
+
+* Redistributions of source code must retain the above copyright notice, this
+ list of conditions and the following disclaimer.
+
+* Redistributions in binary form must reproduce the above copyright notice,
+ this list of conditions and the following disclaimer in the documentation
+ and/or other materials provided with the distribution.
+
+----------------------------- LICENSE FOR DCGAN --------------------------------
+BSD License
+
+For dcgan.torch software
+
+Copyright (c) 2015, Facebook, Inc. All rights reserved.
+
+Redistribution and use in source and binary forms, with or without modification, are permitted provided that the following conditions are met:
+
+Redistributions of source code must retain the above copyright notice, this list of conditions and the following disclaimer.
+
+Redistributions in binary form must reproduce the above copyright notice, this list of conditions and the following disclaimer in the documentation and/or other materials provided with the distribution.
+
+Neither the name Facebook nor the names of its contributors may be used to endorse or promote products derived from this software without specific prior written permission.
+
+THIS SOFTWARE IS PROVIDED BY THE COPYRIGHT HOLDERS AND CONTRIBUTORS "AS IS" AND ANY EXPRESS OR IMPLIED WARRANTIES, INCLUDING, BUT NOT LIMITED TO, THE IMPLIED WARRANTIES OF MERCHANTABILITY AND FITNESS FOR A PARTICULAR PURPOSE ARE DISCLAIMED. IN NO EVENT SHALL THE COPYRIGHT HOLDER OR CONTRIBUTORS BE LIABLE FOR ANY DIRECT, INDIRECT, INCIDENTAL, SPECIAL, EXEMPLARY, OR CONSEQUENTIAL DAMAGES (INCLUDING, BUT NOT LIMITED TO, PROCUREMENT OF SUBSTITUTE GOODS OR SERVICES; LOSS OF USE, DATA, OR PROFITS; OR BUSINESS INTERRUPTION) HOWEVER CAUSED AND ON ANY THEORY OF LIABILITY, WHETHER IN CONTRACT, STRICT LIABILITY, OR TORT (INCLUDING NEGLIGENCE OR OTHERWISE) ARISING IN ANY WAY OUT OF THE USE OF THIS SOFTWARE, EVEN IF ADVISED OF THE POSSIBILITY OF SUCH DAMAGE.
diff --git a/pix2pix_vgg/README.md b/pix2pix_vgg/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..9aae675b0c30cadb61c2c82064d138cd81a79d44
--- /dev/null
+++ b/pix2pix_vgg/README.md
@@ -0,0 +1,308 @@
+
 +
+
+
+# CycleGAN and pix2pix in PyTorch
+
+**Udpate in 2025**: we recently updated the code to support Python 3.11 and PyTorch 2.4. It also supports DDP for single-machine multiple-GPU training. (Please use `torchrun --nproc_per_node=4 train.py ...`)
+
+**New**: Please check out [img2img-turbo](https://github.com/GaParmar/img2img-turbo) repo that includes both pix2pix-turbo and CycleGAN-Turbo. Our new one-step image-to-image translation methods can support both paired and unpaired training and produce better results by leveraging the pre-trained StableDiffusion-Turbo model. The inference time for 512x512 image is 0.29 sec on A6000 and 0.11 sec on A100.
+
+Please check out [contrastive-unpaired-translation](https://github.com/taesungp/contrastive-unpaired-translation) (CUT), our new unpaired image-to-image translation model that enables fast and memory-efficient training.
+
+We provide PyTorch implementations for both unpaired and paired image-to-image translation.
+
+The code was written by [Jun-Yan Zhu](https://github.com/junyanz) and [Taesung Park](https://github.com/taesungp), and supported by [Tongzhou Wang](https://github.com/SsnL).
+
+This PyTorch implementation produces results comparable to or better than our original Torch software. If you would like to reproduce the same results as in the papers, check out the original [CycleGAN Torch](https://github.com/junyanz/CycleGAN) and [pix2pix Torch](https://github.com/phillipi/pix2pix) code in Lua/Torch.
+
+**Note**: The current software works well with PyTorch 2.4+. Check out the older [branch](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/tree/pytorch0.3.1) that supports PyTorch 0.1-0.3.
+
+You may find useful information in [training/test tips](docs/tips.md) and [frequently asked questions](docs/qa.md). To implement custom models and datasets, check out our [templates](#custom-model-and-dataset). To help users better understand and adapt our codebase, we provide an [overview](docs/overview.md) of the code structure of this repository.
+
+**CycleGAN: [Project](https://junyanz.github.io/CycleGAN/) | [Paper](https://arxiv.org/pdf/1703.10593.pdf) | [Torch](https://github.com/junyanz/CycleGAN) |
+[Tensorflow Core Tutorial](https://www.tensorflow.org/tutorials/generative/cyclegan) | [PyTorch Colab](https://colab.research.google.com/github/junyanz/pytorch-CycleGAN-and-pix2pix/blob/master/CycleGAN.ipynb)**
+
+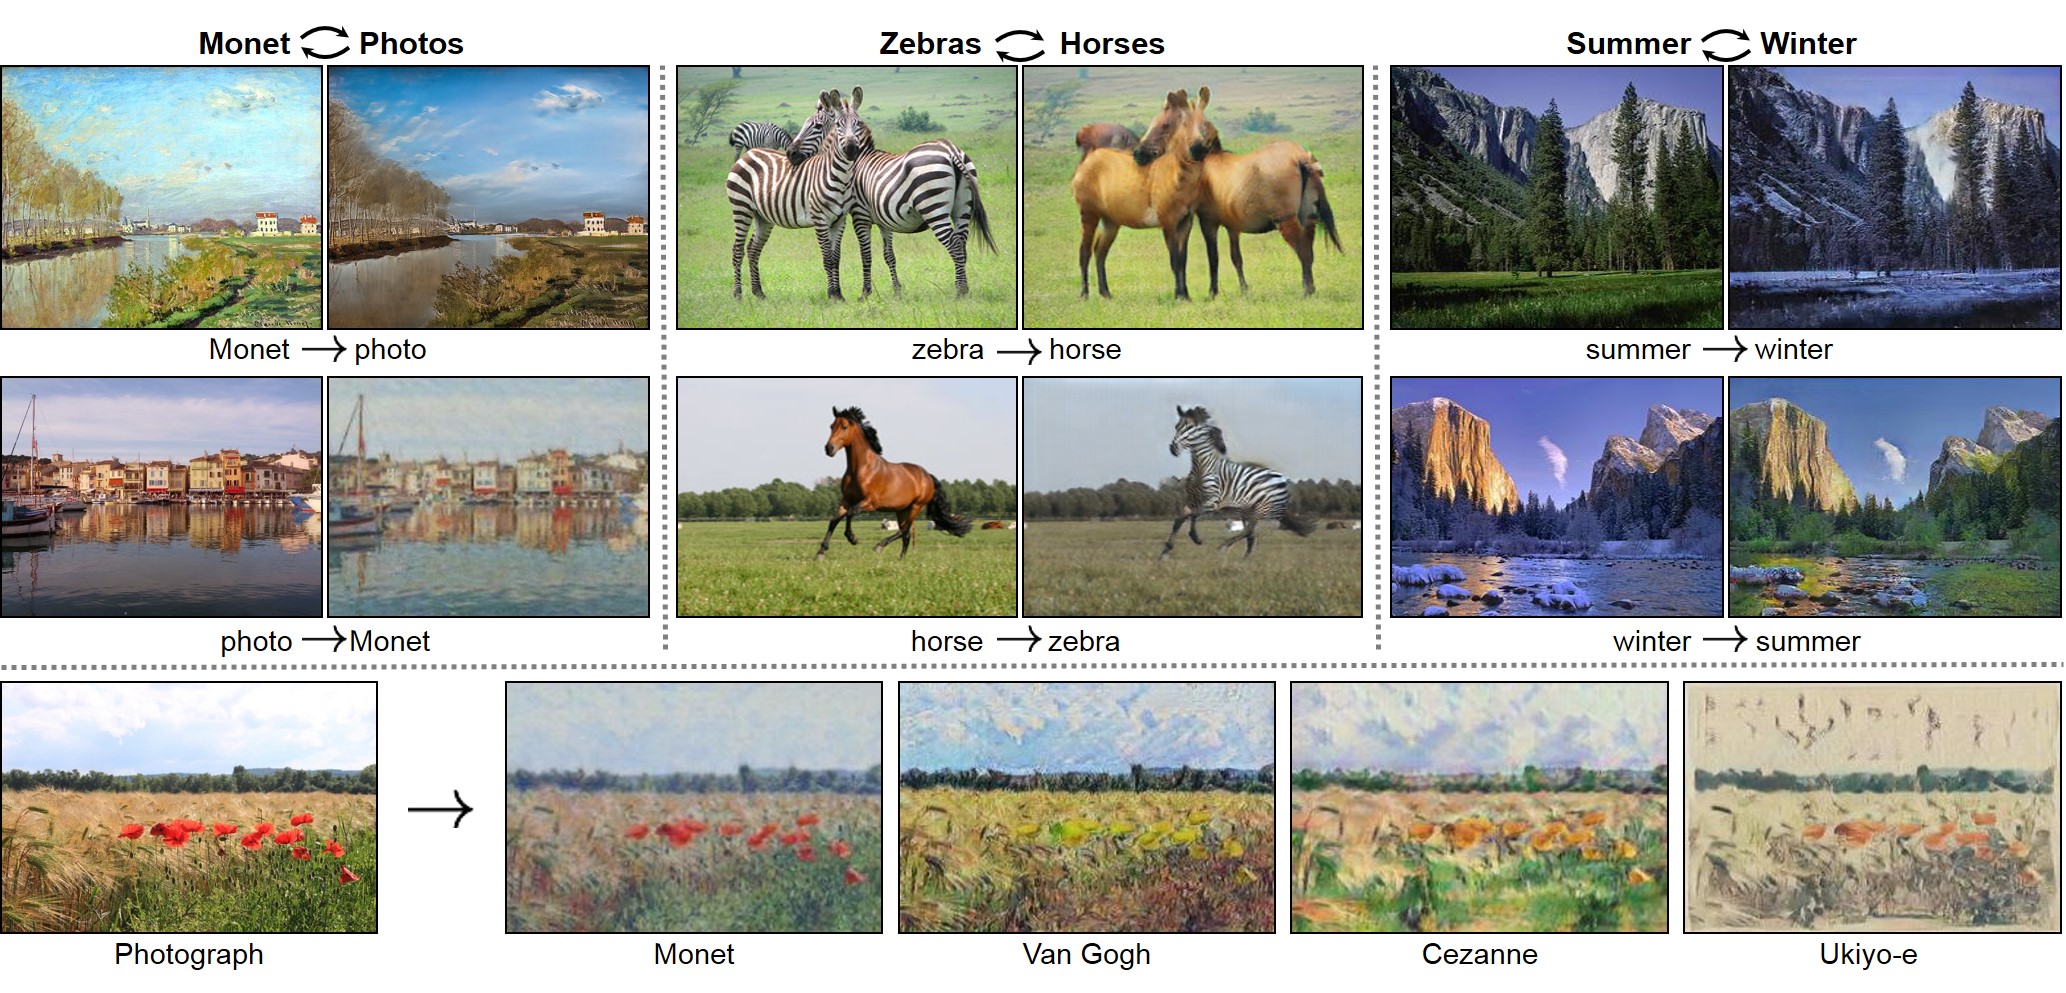 +
+**Pix2pix: [Project](https://phillipi.github.io/pix2pix/) | [Paper](https://arxiv.org/pdf/1611.07004.pdf) | [Torch](https://github.com/phillipi/pix2pix) |
+[Tensorflow Core Tutorial](https://www.tensorflow.org/tutorials/generative/pix2pix) | [PyTorch Colab](https://colab.research.google.com/github/junyanz/pytorch-CycleGAN-and-pix2pix/blob/master/pix2pix.ipynb)**
+
+
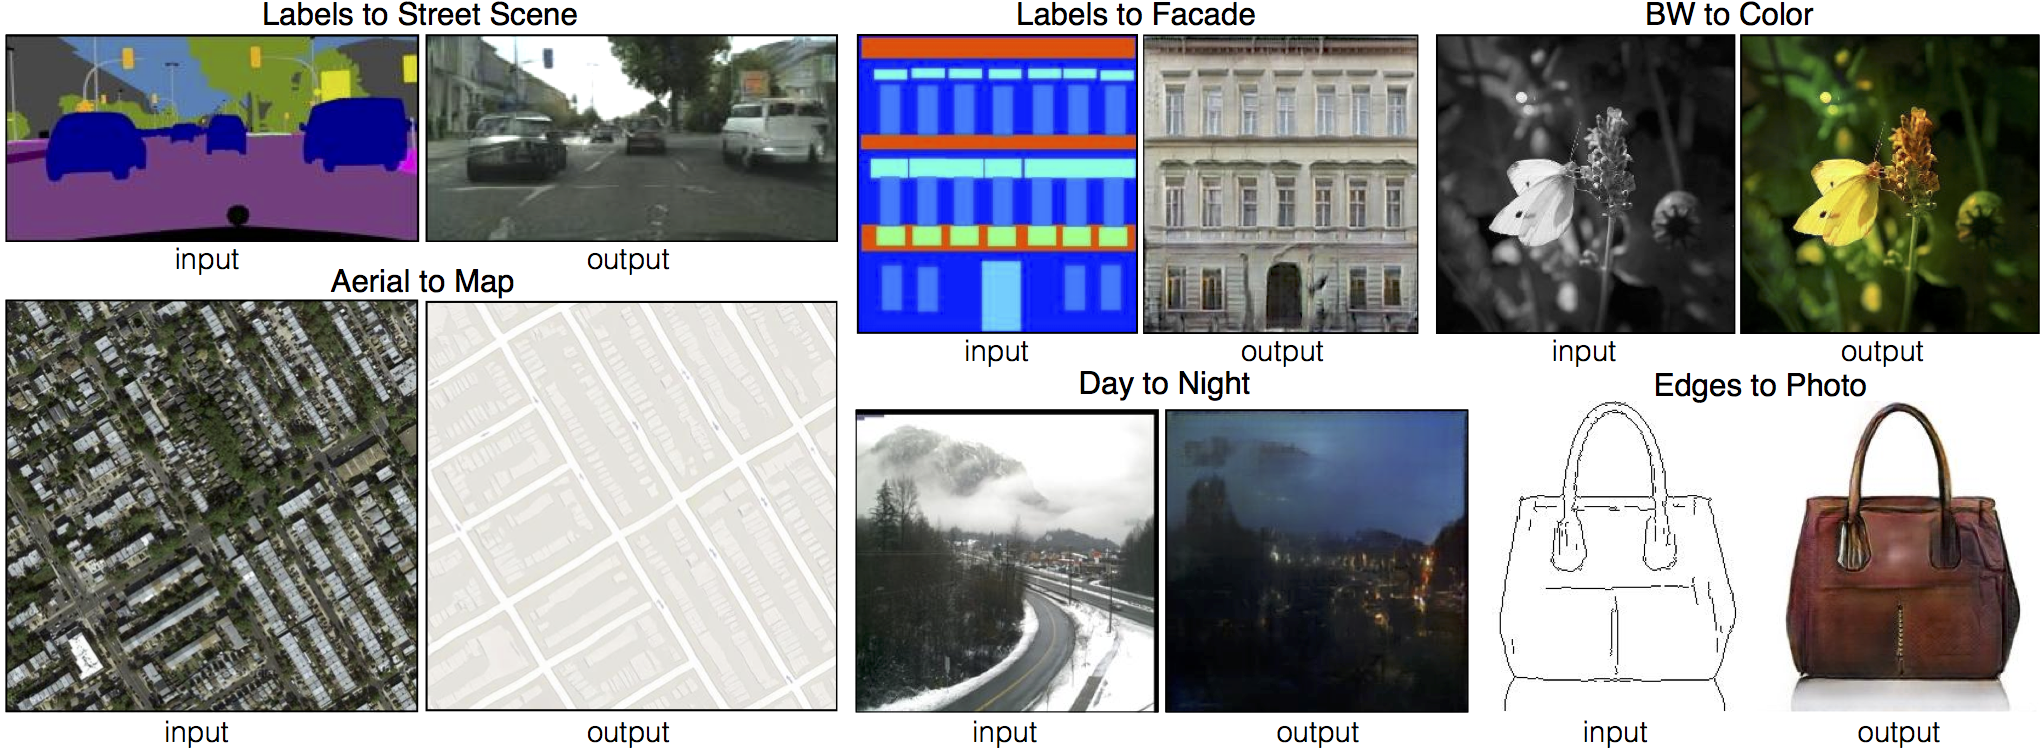 +
+**[EdgesCats Demo](https://affinelayer.com/pixsrv/) | [pix2pix-tensorflow](https://github.com/affinelayer/pix2pix-tensorflow) | by [Christopher Hesse](https://twitter.com/christophrhesse)**
+
+
 +
+If you use this code for your research, please cite:
+
+Unpaired Image-to-Image Translation using Cycle-Consistent Adversarial Networks.
+[Jun-Yan Zhu](https://www.cs.cmu.edu/~junyanz/)\*, [Taesung Park](https://taesung.me/)\*, [Phillip Isola](https://people.eecs.berkeley.edu/~isola/), [Alexei A. Efros](https://people.eecs.berkeley.edu/~efros). In ICCV 2017. (\* equal contributions) [[Bibtex]](https://junyanz.github.io/CycleGAN/CycleGAN.txt)
+
+Image-to-Image Translation with Conditional Adversarial Networks.
+[Phillip Isola](https://people.eecs.berkeley.edu/~isola), [Jun-Yan Zhu](https://www.cs.cmu.edu/~junyanz/), [Tinghui Zhou](https://people.eecs.berkeley.edu/~tinghuiz), [Alexei A. Efros](https://people.eecs.berkeley.edu/~efros). In CVPR 2017. [[Bibtex]](https://www.cs.cmu.edu/~junyanz/projects/pix2pix/pix2pix.bib)
+
+## Talks and Course
+
+pix2pix slides: [keynote](http://efrosgans.eecs.berkeley.edu/CVPR18_slides/pix2pix.key) | [pdf](http://efrosgans.eecs.berkeley.edu/CVPR18_slides/pix2pix.pdf),
+CycleGAN slides: [pptx](http://efrosgans.eecs.berkeley.edu/CVPR18_slides/CycleGAN.pptx) | [pdf](http://efrosgans.eecs.berkeley.edu/CVPR18_slides/CycleGAN.pdf)
+
+CycleGAN course assignment [code](http://www.cs.toronto.edu/~rgrosse/courses/csc321_2018/assignments/a4-code.zip) and [handout](http://www.cs.toronto.edu/~rgrosse/courses/csc321_2018/assignments/a4-handout.pdf) designed by Prof. [Roger Grosse](http://www.cs.toronto.edu/~rgrosse/) for [CSC321](http://www.cs.toronto.edu/~rgrosse/courses/csc321_2018/) "Intro to Neural Networks and Machine Learning" at University of Toronto. Please contact the instructor if you would like to adopt it in your course.
+
+## Colab Notebook
+
+TensorFlow Core CycleGAN Tutorial: [Google Colab](https://colab.research.google.com/github/tensorflow/docs/blob/master/site/en/tutorials/generative/cyclegan.ipynb) | [Code](https://github.com/tensorflow/docs/blob/master/site/en/tutorials/generative/cyclegan.ipynb)
+
+TensorFlow Core pix2pix Tutorial: [Google Colab](https://colab.research.google.com/github/tensorflow/docs/blob/master/site/en/tutorials/generative/pix2pix.ipynb) | [Code](https://github.com/tensorflow/docs/blob/master/site/en/tutorials/generative/pix2pix.ipynb)
+
+PyTorch Colab notebook: [CycleGAN](https://colab.research.google.com/github/junyanz/pytorch-CycleGAN-and-pix2pix/blob/master/CycleGAN.ipynb) and [pix2pix](https://colab.research.google.com/github/junyanz/pytorch-CycleGAN-and-pix2pix/blob/master/pix2pix.ipynb)
+
+ZeroCostDL4Mic Colab notebook: [CycleGAN](https://colab.research.google.com/github/HenriquesLab/ZeroCostDL4Mic/blob/master/Colab_notebooks_Beta/CycleGAN_ZeroCostDL4Mic.ipynb) and [pix2pix](https://colab.research.google.com/github/HenriquesLab/ZeroCostDL4Mic/blob/master/Colab_notebooks_Beta/pix2pix_ZeroCostDL4Mic.ipynb)
+
+## Other implementations
+
+### CycleGAN
+
+ [Tensorflow] (by Harry Yang),
+[Tensorflow] (by Archit Rathore),
+[Tensorflow] (by Van Huy),
+[Tensorflow] (by Xiaowei Hu),
+ [Tensorflow2] (by Zhenliang He),
+ [TensorLayer1.0] (by luoxier),
+ [TensorLayer2.0] (by zsdonghao),
+[Chainer] (by Yanghua Jin),
+[Minimal PyTorch] (by yunjey),
+[Mxnet] (by Ldpe2G),
+[lasagne/Keras] (by tjwei),
+[Keras] (by Simon Karlsson),
+[OneFlow] (by Ldpe2G)
+
+
+
+### pix2pix
+
+ [Tensorflow] (by Christopher Hesse),
+[Tensorflow] (by Eyyüb Sariu),
+ [Tensorflow (face2face)] (by Dat Tran),
+ [Tensorflow (film)] (by Arthur Juliani),
+[Tensorflow (zi2zi)] (by Yuchen Tian),
+[Chainer] (by mattya),
+[tf/torch/keras/lasagne] (by tjwei),
+[Pytorch] (by taey16)
+
+
+
+## Prerequisites
+
+- Linux or macOS
+- Python 3
+- CPU or NVIDIA GPU + CUDA CuDNN
+
+## Getting Started
+
+### Installation
+
+- Clone this repo:
+
+```bash
+git clone https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix
+cd pytorch-CycleGAN-and-pix2pix
+```
+
+- Install [PyTorch](http://pytorch.org) and other dependencies. For Conda users, you can create a new Conda environment by
+
+```bash
+conda env create -f environment.yml
+```
+
+and then activate the environment by
+
+```bash
+conda activate pytorch-img2img
+```
+
+- For Docker users, we provide the pre-built Docker image and Dockerfile. Please refer to our [Docker](docs/docker.md) page.
+- For Repl users, please click [](https://repl.it/github/junyanz/pytorch-CycleGAN-and-pix2pix).
+
+### CycleGAN train/test
+
+- Download a CycleGAN dataset (e.g. maps):
+
+```bash
+bash ./datasets/download_cyclegan_dataset.sh maps
+```
+
+- To log training progress and test images to W&B dashboard, set the `--use_wandb` flag with training script
+- Train a model:
+
+```bash
+#!./scripts/train_cyclegan.sh
+python train.py --dataroot ./datasets/maps --name maps_cyclegan --model cycle_gan --use_wandb
+```
+
+To see more intermediate results, check out `./checkpoints/maps_cyclegan/web/index.html`.
+
+- Test the model:
+
+```bash
+#!./scripts/test_cyclegan.sh
+python test.py --dataroot ./datasets/maps --name maps_cyclegan --model cycle_gan
+```
+
+- The test results will be saved to a html file here: `./results/maps_cyclegan/latest_test/index.html`.
+
+### pix2pix train/test
+
+- Download a pix2pix dataset (e.g.[facades](http://cmp.felk.cvut.cz/~tylecr1/facade/)):
+
+```bash
+bash ./datasets/download_pix2pix_dataset.sh facades
+```
+
+- To log training progress and test images to W&B dashboard, set the `--use_wandb` flag with training script
+- Train a model:
+
+```bash
+#!./scripts/train_pix2pix.sh
+python train.py --dataroot ./datasets/facades --name facades_pix2pix --model pix2pix --direction BtoA --use_wandb
+```
+
+To see more intermediate results, check out `./checkpoints/facades_pix2pix/web/index.html`.
+
+- Test the model (`bash ./scripts/test_pix2pix.sh`):
+
+```bash
+#!./scripts/test_pix2pix.sh
+python test.py --dataroot ./datasets/facades --name facades_pix2pix --model pix2pix --direction BtoA
+```
+
+- The test results will be saved to a html file here: `./results/facades_pix2pix/test_latest/index.html`. You can find more scripts at `scripts` directory.
+- To train and test pix2pix-based colorization models, please add `--model colorization` and `--dataset_mode colorization`. See our training [tips](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/blob/master/docs/tips.md#notes-on-colorization) for more details.
+
+### Apply a pre-trained model (CycleGAN)
+
+- You can download a pretrained model (e.g. horse2zebra) with the following script:
+
+```bash
+bash ./scripts/download_cyclegan_model.sh horse2zebra
+```
+
+- The pretrained model is saved at `./checkpoints/{name}_pretrained/latest_net_G.pth`. Check [here](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/blob/master/scripts/download_cyclegan_model.sh#L3) for all the available CycleGAN models.
+- To test the model, you also need to download the horse2zebra dataset:
+
+```bash
+bash ./datasets/download_cyclegan_dataset.sh horse2zebra
+```
+
+- Then generate the results using
+
+```bash
+python test.py --dataroot datasets/horse2zebra/testA --name horse2zebra_pretrained --model test --no_dropout
+```
+
+- The option `--model test` is used for generating results of CycleGAN only for one side. This option will automatically set `--dataset_mode single`, which only loads the images from one set. On the contrary, using `--model cycle_gan` requires loading and generating results in both directions, which is sometimes unnecessary. The results will be saved at `./results/`. Use `--results_dir {directory_path_to_save_result}` to specify the results directory.
+
+- For pix2pix and your own models, you need to explicitly specify `--netG`, `--norm`, `--no_dropout` to match the generator architecture of the trained model. See this [FAQ](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/blob/master/docs/qa.md#runtimeerror-errors-in-loading-state_dict-812-671461-296) for more details.
+
+### Apply a pre-trained model (pix2pix)
+
+Download a pre-trained model with `./scripts/download_pix2pix_model.sh`.
+
+- Check [here](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/blob/master/scripts/download_pix2pix_model.sh#L3) for all the available pix2pix models. For example, if you would like to download label2photo model on the Facades dataset,
+
+```bash
+bash ./scripts/download_pix2pix_model.sh facades_label2photo
+```
+
+- Download the pix2pix facades datasets:
+
+```bash
+bash ./datasets/download_pix2pix_dataset.sh facades
+```
+
+- Then generate the results using
+
+```bash
+python test.py --dataroot ./datasets/facades/ --direction BtoA --model pix2pix --name facades_label2photo_pretrained
+```
+
+- Note that we specified `--direction BtoA` as Facades dataset's A to B direction is photos to labels.
+
+- If you would like to apply a pre-trained model to a collection of input images (rather than image pairs), please use `--model test` option. See `./scripts/test_single.sh` for how to apply a model to Facade label maps (stored in the directory `facades/testB`).
+
+- See a list of currently available models at `./scripts/download_pix2pix_model.sh`
+
+### Multi-GPU training
+
+To train a model on multiple GPUs, please use `torchrun --nproc_per_node=4 train.py ...` instead of `python train.py ...`. We also need to use synchronized batchnorm by setting `--norm sync_batch` (or `--norm sync_instance` for instance normgalization). The `--norm batch` is not compatible with DDP.
+
+## [Docker](docs/docker.md)
+
+We provide the pre-built Docker image and Dockerfile that can run this code repo. See [docker](docs/docker.md).
+
+## [Datasets](docs/datasets.md)
+
+Download pix2pix/CycleGAN datasets and create your own datasets.
+
+## [Training/Test Tips](docs/tips.md)
+
+Best practice for training and testing your models.
+
+## [Frequently Asked Questions](docs/qa.md)
+
+Before you post a new question, please first look at the above Q & A and existing GitHub issues.
+
+## Custom Model and Dataset
+
+If you plan to implement custom models and dataset for your new applications, we provide a dataset [template](data/template_dataset.py) and a model [template](models/template_model.py) as a starting point.
+
+## [Code structure](docs/overview.md)
+
+To help users better understand and use our code, we briefly overview the functionality and implementation of each package and each module.
+
+## Pull Request
+
+You are always welcome to contribute to this repository by sending a [pull request](https://help.github.com/articles/about-pull-requests/).
+Please run `flake8 --ignore E501 .` and `pytest scripts/test_before_push.py -v` before you commit the code. Please also update the code structure [overview](docs/overview.md) accordingly if you add or remove files.
+
+## Citation
+
+If you use this code for your research, please cite our papers.
+
+```
+@inproceedings{CycleGAN2017,
+ title={Unpaired Image-to-Image Translation using Cycle-Consistent Adversarial Networks},
+ author={Zhu, Jun-Yan and Park, Taesung and Isola, Phillip and Efros, Alexei A},
+ booktitle={Computer Vision (ICCV), 2017 IEEE International Conference on},
+ year={2017}
+}
+
+
+@inproceedings{isola2017image,
+ title={Image-to-Image Translation with Conditional Adversarial Networks},
+ author={Isola, Phillip and Zhu, Jun-Yan and Zhou, Tinghui and Efros, Alexei A},
+ booktitle={Computer Vision and Pattern Recognition (CVPR), 2017 IEEE Conference on},
+ year={2017}
+}
+```
+
+## Other Languages
+
+[Spanish](docs/README_es.md)
+
+## Related Projects
+
+[img2img-turbo](https://github.com/GaParmar/img2img-turbo)
+[contrastive-unpaired-translation](https://github.com/taesungp/contrastive-unpaired-translation) (CUT)
+[CycleGAN-Torch](https://github.com/junyanz/CycleGAN) |
+[pix2pix-Torch](https://github.com/phillipi/pix2pix) | [pix2pixHD](https://github.com/NVIDIA/pix2pixHD)|
+[BicycleGAN](https://github.com/junyanz/BicycleGAN) | [vid2vid](https://tcwang0509.github.io/vid2vid/) | [SPADE/GauGAN](https://github.com/NVlabs/SPADE)
+[iGAN](https://github.com/junyanz/iGAN) | [GAN Dissection](https://github.com/CSAILVision/GANDissect) | [GAN Paint](http://ganpaint.io/)
+
+## Cat Paper Collection
+
+If you love cats, and love reading cool graphics, vision, and learning papers, please check out the Cat Paper [Collection](https://github.com/junyanz/CatPapers).
+
+## Acknowledgments
+
+Our code is inspired by [pytorch-DCGAN](https://github.com/pytorch/examples/tree/master/dcgan).
diff --git a/pix2pix_vgg/data/__init__.py b/pix2pix_vgg/data/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..3e4ea53aeac8ca58fb79229ce2c077873a76152d
--- /dev/null
+++ b/pix2pix_vgg/data/__init__.py
@@ -0,0 +1,107 @@
+"""This package includes all the modules related to data loading and preprocessing
+
+ To add a custom dataset class called 'dummy', you need to add a file called 'dummy_dataset.py' and define a subclass 'DummyDataset' inherited from BaseDataset.
+ You need to implement four functions:
+ -- <__init__>: initialize the class, first call BaseDataset.__init__(self, opt).
+ -- <__len__>: return the size of dataset.
+ -- <__getitem__>: get a data point from data loader.
+ -- : (optionally) add dataset-specific options and set default options.
+
+Now you can use the dataset class by specifying flag '--dataset_mode dummy'.
+See our template dataset class 'template_dataset.py' for more details.
+"""
+
+import importlib
+import torch.utils.data
+from torch.utils.data.distributed import DistributedSampler
+import torch.distributed as dist
+import os
+from data.base_dataset import BaseDataset
+
+
+def find_dataset_using_name(dataset_name):
+ """Import the module "data/[dataset_name]_dataset.py".
+
+ In the file, the class called DatasetNameDataset() will
+ be instantiated. It has to be a subclass of BaseDataset,
+ and it is case-insensitive.
+ """
+ dataset_filename = "data." + dataset_name + "_dataset"
+ datasetlib = importlib.import_module(dataset_filename)
+
+ dataset = None
+ target_dataset_name = dataset_name.replace("_", "") + "dataset"
+ for name, cls in datasetlib.__dict__.items():
+ if name.lower() == target_dataset_name.lower() and issubclass(cls, BaseDataset):
+ dataset = cls
+
+ if dataset is None:
+ raise NotImplementedError("In %s.py, there should be a subclass of BaseDataset with class name that matches %s in lowercase." % (dataset_filename, target_dataset_name))
+
+ return dataset
+
+
+def get_option_setter(dataset_name):
+ """Return the static method of the dataset class."""
+ dataset_class = find_dataset_using_name(dataset_name)
+ return dataset_class.modify_commandline_options
+
+
+def create_dataset(opt):
+ """Create a dataset given the option.
+
+ This function wraps the class CustomDatasetDataLoader.
+ This is the main interface between this package and 'train.py'/'test.py'
+
+ Example:
+ >>> from data import create_dataset
+ >>> dataset = create_dataset(opt)
+ """
+ data_loader = CustomDatasetDataLoader(opt)
+ dataset = data_loader.load_data()
+ return dataset
+
+
+class CustomDatasetDataLoader:
+ """Wrapper class of Dataset class that performs multi-threaded data loading"""
+
+ def __init__(self, opt):
+ """Initialize this class
+
+ Step 1: create a dataset instance given the name [dataset_mode]
+ Step 2: create a multi-threaded data loader.
+ """
+ self.opt = opt
+ dataset_class = find_dataset_using_name(opt.dataset_mode)
+ self.dataset = dataset_class(opt)
+ print("dataset [%s] was created" % type(self.dataset).__name__)
+
+ # Use DistributedSampler for DDP training
+ if "LOCAL_RANK" in os.environ:
+ print(f'create DDP sampler on rank {int(os.environ["LOCAL_RANK"])}')
+ self.sampler = DistributedSampler(self.dataset, shuffle=not opt.serial_batches)
+ shuffle = False # DistributedSampler handles shuffling
+ else:
+ self.sampler = None
+ shuffle = not opt.serial_batches
+
+ self.dataloader = torch.utils.data.DataLoader(self.dataset, batch_size=opt.batch_size, shuffle=shuffle, sampler=self.sampler, num_workers=int(opt.num_threads))
+
+ def load_data(self):
+ return self
+
+ def __len__(self):
+ """Return the number of data in the dataset"""
+ return min(len(self.dataset), self.opt.max_dataset_size)
+
+ def __iter__(self):
+ """Return a batch of data"""
+ for i, data in enumerate(self.dataloader):
+ if i * self.opt.batch_size >= self.opt.max_dataset_size:
+ break
+ yield data
+
+ def set_epoch(self, epoch):
+ """Set epoch for DistributedSampler to ensure proper shuffling"""
+ if self.sampler is not None:
+ self.sampler.set_epoch(epoch)
diff --git a/pix2pix_vgg/data/__pycache__/__init__.cpython-312.pyc b/pix2pix_vgg/data/__pycache__/__init__.cpython-312.pyc
new file mode 100644
index 0000000000000000000000000000000000000000..df4059f9c3e6809cb8e961570065034230916d67
Binary files /dev/null and b/pix2pix_vgg/data/__pycache__/__init__.cpython-312.pyc differ
diff --git a/pix2pix_vgg/data/__pycache__/aligned_dataset.cpython-312.pyc b/pix2pix_vgg/data/__pycache__/aligned_dataset.cpython-312.pyc
new file mode 100644
index 0000000000000000000000000000000000000000..5cf25d09df88a268b8ff9de5eb5b143a57d083b6
Binary files /dev/null and b/pix2pix_vgg/data/__pycache__/aligned_dataset.cpython-312.pyc differ
diff --git a/pix2pix_vgg/data/__pycache__/base_dataset.cpython-312.pyc b/pix2pix_vgg/data/__pycache__/base_dataset.cpython-312.pyc
new file mode 100644
index 0000000000000000000000000000000000000000..bb50b485eac4093d10d3f4e62973d0be0086af6f
Binary files /dev/null and b/pix2pix_vgg/data/__pycache__/base_dataset.cpython-312.pyc differ
diff --git a/pix2pix_vgg/data/__pycache__/image_folder.cpython-312.pyc b/pix2pix_vgg/data/__pycache__/image_folder.cpython-312.pyc
new file mode 100644
index 0000000000000000000000000000000000000000..7913cf8c763916312417467c3425241ae4a05138
Binary files /dev/null and b/pix2pix_vgg/data/__pycache__/image_folder.cpython-312.pyc differ
diff --git a/pix2pix_vgg/data/aligned_dataset.py b/pix2pix_vgg/data/aligned_dataset.py
new file mode 100644
index 0000000000000000000000000000000000000000..df652ff5a0bf88ef2be6a75d087f12841a8fa32e
--- /dev/null
+++ b/pix2pix_vgg/data/aligned_dataset.py
@@ -0,0 +1,132 @@
+import os
+import numpy as np
+import torch
+from PIL import Image
+import torchvision.transforms.functional as TF
+
+from data.base_dataset import BaseDataset, get_transform, get_params
+from data.image_folder import make_dataset
+
+
+class AlignedDataset(BaseDataset):
+ """Paired dataset (A|B in one image). Also loads a per-sample mask aligned to B."""
+
+ def __init__(self, opt):
+ BaseDataset.__init__(self, opt)
+ self.dir_AB = os.path.join(opt.dataroot, opt.phase)
+ self.AB_paths = sorted(make_dataset(self.dir_AB, opt.max_dataset_size))
+ assert self.opt.load_size >= self.opt.crop_size
+ self.input_nc = self.opt.output_nc if self.opt.direction == "BtoA" else self.opt.input_nc
+ self.output_nc = self.opt.input_nc if self.opt.direction == "BtoA" else self.opt.output_nc
+
+ # 这些开关可在命令行给(都有默认)
+ self.use_mask_condition = getattr(self.opt, "use_mask_condition", False) # 是否把 mask 拼到 A 作为条件
+ self.mask_hard = getattr(self.opt, "mask_hard", True) # 是否把 mask 二值化
+ self.mask_thresh = getattr(self.opt, "mask_thresh", 0.5) # 二值阈值
+
+ def __len__(self):
+ return len(self.AB_paths)
+
+ # -------------------- 关键:按与 B 完全一致的参数变换 mask --------------------
+ def _apply_mask_transform(self, mask_img: Image.Image, params):
+ """
+ 对 mask 应用与 B 完全一致的几何变换;插值一律用 NEAREST,避免灰边。
+ 输出 [1,H,W] 的 float32,范围 0~1(可选二值化)。
+ """
+ preprocess = getattr(self.opt, "preprocess", "resize_and_crop")
+ load_size = getattr(self.opt, "load_size", None)
+ crop_size = getattr(self.opt, "crop_size", None)
+
+ # 1) resize / scale_width / crop(与 B 同步)
+ if preprocess == "resize_and_crop":
+ assert load_size is not None and crop_size is not None
+ mask_img = mask_img.resize((load_size, load_size), Image.NEAREST)
+ x, y = params["crop_pos"]
+ mask_img = mask_img.crop((x, y, x + crop_size, y + crop_size))
+
+ elif preprocess == "scale_width_and_crop":
+ assert load_size is not None and crop_size is not None
+ ow, oh = mask_img.size
+ if ow != load_size:
+ new_h = int(round(oh * load_size / ow))
+ mask_img = mask_img.resize((load_size, new_h), Image.NEAREST)
+ x, y = params["crop_pos"]
+ mask_img = mask_img.crop((x, y, x + crop_size, y + crop_size))
+
+ elif preprocess == "resize":
+ assert load_size is not None
+ mask_img = mask_img.resize((load_size, load_size), Image.NEAREST)
+
+ elif preprocess == "crop":
+ assert crop_size is not None
+ x, y = params["crop_pos"]
+ mask_img = mask_img.crop((x, y, x + crop_size, y + crop_size))
+
+ elif preprocess == "none":
+ pass # 不做几何变化
+
+ # 2) flip(与 B 同步)
+ if (not self.opt.no_flip) and params.get("flip", False):
+ mask_img = TF.hflip(mask_img)
+
+ # 3) ToTensor → float32 的 0~1
+ m = torch.from_numpy(np.array(mask_img, dtype=np.uint8)) # [H,W], 0..255
+ m = m.float().div(255.0)
+
+ # 4) (可选)二值化
+ if self.mask_hard:
+ m = (m >= self.mask_thresh).float()
+
+ # [1,H,W]
+ return m.unsqueeze(0)
+
+ # -------------------------------------------------------------------------
+
+ def __getitem__(self, index):
+ """Return a dict with A, B, mask_B (and optionally A_cond)."""
+ # 读取 A|B 拼接图
+ AB_path = self.AB_paths[index]
+ AB = Image.open(AB_path).convert("RGB")
+
+ # 拆分 A、B
+ w, h = AB.size
+ w2 = int(w / 2)
+ A = AB.crop((0, 0, w2, h))
+ B = AB.crop((w2, 0, w, h))
+
+ # 统一参数,保证 A、B、mask 变换一致
+ transform_params = get_params(self.opt, A.size)
+ A_transform = get_transform(self.opt, transform_params, grayscale=(self.input_nc == 1))
+ B_transform = get_transform(self.opt, transform_params, grayscale=(self.output_nc == 1))
+
+ A = A_transform(A) # [C,H,W], float
+ B = B_transform(B) # [C,H,W], float
+
+ # 读取并对齐 mask(与 B 对齐)
+ mask = None
+ if getattr(self.opt, "masks_dir", ""):
+ stem = os.path.splitext(os.path.basename(AB_path))[0]
+ for ext in (".png", ".jpg", ".jpeg", ".PNG", ".JPG", ".JPEG"):
+ mp = os.path.join(self.opt.masks_dir, stem + ext)
+ if os.path.exists(mp):
+ mimg = Image.open(mp).convert("L")
+ mask = self._apply_mask_transform(mimg, transform_params) # [1,H,W], 0~1
+ break
+
+ # 若没有 mask,给全 0(尺寸与 B 一致)
+ if mask is None:
+ mask = torch.zeros_like(B[:1, :, :]) # [1,H,W]
+
+ out = {
+ "A": A,
+ "B": B,
+ "A_paths": AB_path,
+ "B_paths": AB_path,
+ "mask_B": mask, # [1,H,W], float32, 0~1(可能是二值)
+ }
+
+ # 可选:直接返回拼好的条件输入;若你在 model 里拼,这块可不要
+ if self.use_mask_condition:
+ out["A_cond"] = torch.cat([A, mask], dim=0) # [C+1,H,W]
+
+ return out
\ No newline at end of file
diff --git a/pix2pix_vgg/data/base_dataset.py b/pix2pix_vgg/data/base_dataset.py
new file mode 100644
index 0000000000000000000000000000000000000000..016bd89d727a498e6e90667a7f5fe582f7ece195
--- /dev/null
+++ b/pix2pix_vgg/data/base_dataset.py
@@ -0,0 +1,167 @@
+"""This module implements an abstract base class (ABC) 'BaseDataset' for datasets.
+
+It also includes common transformation functions (e.g., get_transform, __scale_width), which can be later used in subclasses.
+"""
+
+import random
+import numpy as np
+import torch.utils.data as data
+from PIL import Image
+import torchvision.transforms as transforms
+from abc import ABC, abstractmethod
+
+
+class BaseDataset(data.Dataset, ABC):
+ """This class is an abstract base class (ABC) for datasets.
+
+ To create a subclass, you need to implement the following four functions:
+ -- <__init__>: initialize the class, first call BaseDataset.__init__(self, opt).
+ -- <__len__>: return the size of dataset.
+ -- <__getitem__>: get a data point.
+ -- : (optionally) add dataset-specific options and set default options.
+ """
+
+ def __init__(self, opt):
+ """Initialize the class; save the options in the class
+
+ Parameters:
+ opt (Option class)-- stores all the experiment flags; needs to be a subclass of BaseOptions
+ """
+ self.opt = opt
+ self.root = opt.dataroot
+
+ @staticmethod
+ def modify_commandline_options(parser, is_train):
+ """Add new dataset-specific options, and rewrite default values for existing options.
+
+ Parameters:
+ parser -- original option parser
+ is_train (bool) -- whether training phase or test phase. You can use this flag to add training-specific or test-specific options.
+
+ Returns:
+ the modified parser.
+ """
+ return parser
+
+ @abstractmethod
+ def __len__(self):
+ """Return the total number of images in the dataset."""
+ return 0
+
+ @abstractmethod
+ def __getitem__(self, index):
+ """Return a data point and its metadata information.
+
+ Parameters:
+ index - - a random integer for data indexing
+
+ Returns:
+ a dictionary of data with their names. It ususally contains the data itself and its metadata information.
+ """
+ pass
+
+
+def get_params(opt, size):
+ w, h = size
+ new_h = h
+ new_w = w
+ if opt.preprocess == "resize_and_crop":
+ new_h = new_w = opt.load_size
+ elif opt.preprocess == "scale_width_and_crop":
+ new_w = opt.load_size
+ new_h = opt.load_size * h // w
+
+ x = random.randint(0, np.maximum(0, new_w - opt.crop_size))
+ y = random.randint(0, np.maximum(0, new_h - opt.crop_size))
+
+ flip = random.random() > 0.5
+
+ return {"crop_pos": (x, y), "flip": flip}
+
+
+def get_transform(opt, params=None, grayscale=False, method=transforms.InterpolationMode.BICUBIC, convert=True):
+ transform_list = []
+ if grayscale:
+ transform_list.append(transforms.Grayscale(1))
+ if "resize" in opt.preprocess:
+ osize = [opt.load_size, opt.load_size]
+ transform_list.append(transforms.Resize(osize, method))
+ elif "scale_width" in opt.preprocess:
+ transform_list.append(transforms.Lambda(lambda img: __scale_width(img, opt.load_size, opt.crop_size, method)))
+
+ if "crop" in opt.preprocess:
+ if params is None:
+ transform_list.append(transforms.RandomCrop(opt.crop_size))
+ else:
+ transform_list.append(transforms.Lambda(lambda img: __crop(img, params["crop_pos"], opt.crop_size)))
+
+ if opt.preprocess == "none":
+ transform_list.append(transforms.Lambda(lambda img: __make_power_2(img, base=4, method=method)))
+
+ if not opt.no_flip:
+ if params is None:
+ transform_list.append(transforms.RandomHorizontalFlip())
+ elif params["flip"]:
+ transform_list.append(transforms.Lambda(lambda img: __flip(img, params["flip"])))
+
+ if convert:
+ transform_list += [transforms.ToTensor()]
+ if grayscale:
+ transform_list += [transforms.Normalize((0.5,), (0.5,))]
+ else:
+ transform_list += [transforms.Normalize((0.5, 0.5, 0.5), (0.5, 0.5, 0.5))]
+ return transforms.Compose(transform_list)
+
+
+def __transforms2pil_resize(method):
+ mapper = {
+ transforms.InterpolationMode.BILINEAR: Image.BILINEAR,
+ transforms.InterpolationMode.BICUBIC: Image.BICUBIC,
+ transforms.InterpolationMode.NEAREST: Image.NEAREST,
+ transforms.InterpolationMode.LANCZOS: Image.LANCZOS,
+ }
+ return mapper[method]
+
+
+def __make_power_2(img, base, method=transforms.InterpolationMode.BICUBIC):
+ method = __transforms2pil_resize(method)
+ ow, oh = img.size
+ h = int(round(oh / base) * base)
+ w = int(round(ow / base) * base)
+ if h == oh and w == ow:
+ return img
+
+ __print_size_warning(ow, oh, w, h)
+ return img.resize((w, h), method)
+
+
+def __scale_width(img, target_size, crop_size, method=transforms.InterpolationMode.BICUBIC):
+ method = __transforms2pil_resize(method)
+ ow, oh = img.size
+ if ow == target_size and oh >= crop_size:
+ return img
+ w = target_size
+ h = int(max(target_size * oh / ow, crop_size))
+ return img.resize((w, h), method)
+
+
+def __crop(img, pos, size):
+ ow, oh = img.size
+ x1, y1 = pos
+ tw = th = size
+ if ow > tw or oh > th:
+ return img.crop((x1, y1, x1 + tw, y1 + th))
+ return img
+
+
+def __flip(img, flip):
+ if flip:
+ return img.transpose(Image.FLIP_LEFT_RIGHT)
+ return img
+
+
+def __print_size_warning(ow, oh, w, h):
+ """Print warning information about image size(only print once)"""
+ if not hasattr(__print_size_warning, "has_printed"):
+ print("The image size needs to be a multiple of 4. " "The loaded image size was (%d, %d), so it was adjusted to " "(%d, %d). This adjustment will be done to all images " "whose sizes are not multiples of 4" % (ow, oh, w, h))
+ __print_size_warning.has_printed = True
diff --git a/pix2pix_vgg/data/colorization_dataset.py b/pix2pix_vgg/data/colorization_dataset.py
new file mode 100644
index 0000000000000000000000000000000000000000..a895b303a675bfb345510d11593b9407b69a7cd5
--- /dev/null
+++ b/pix2pix_vgg/data/colorization_dataset.py
@@ -0,0 +1,69 @@
+import os
+from data.base_dataset import BaseDataset, get_transform
+from data.image_folder import make_dataset
+from skimage import color # require skimage
+from PIL import Image
+import numpy as np
+import torchvision.transforms as transforms
+
+
+class ColorizationDataset(BaseDataset):
+ """This dataset class can load a set of natural images in RGB, and convert RGB format into (L, ab) pairs in Lab color space.
+
+ This dataset is required by pix2pix-based colorization model ('--model colorization')
+ """
+
+ @staticmethod
+ def modify_commandline_options(parser, is_train):
+ """Add new dataset-specific options, and rewrite default values for existing options.
+
+ Parameters:
+ parser -- original option parser
+ is_train (bool) -- whether training phase or test phase. You can use this flag to add training-specific or test-specific options.
+
+ Returns:
+ the modified parser.
+
+ By default, the number of channels for input image is 1 (L) and
+ the number of channels for output image is 2 (ab). The direction is from A to B
+ """
+ parser.set_defaults(input_nc=1, output_nc=2, direction="AtoB")
+ return parser
+
+ def __init__(self, opt):
+ """Initialize this dataset class.
+
+ Parameters:
+ opt (Option class) -- stores all the experiment flags; needs to be a subclass of BaseOptions
+ """
+ BaseDataset.__init__(self, opt)
+ self.dir = os.path.join(opt.dataroot, opt.phase)
+ self.AB_paths = sorted(make_dataset(self.dir, opt.max_dataset_size))
+ assert opt.input_nc == 1 and opt.output_nc == 2 and opt.direction == "AtoB"
+ self.transform = get_transform(self.opt, convert=False)
+
+ def __getitem__(self, index):
+ """Return a data point and its metadata information.
+
+ Parameters:
+ index - - a random integer for data indexing
+
+ Returns a dictionary that contains A, B, A_paths and B_paths
+ A (tensor) - - the L channel of an image
+ B (tensor) - - the ab channels of the same image
+ A_paths (str) - - image paths
+ B_paths (str) - - image paths (same as A_paths)
+ """
+ path = self.AB_paths[index]
+ im = Image.open(path).convert("RGB")
+ im = self.transform(im)
+ im = np.array(im)
+ lab = color.rgb2lab(im).astype(np.float32)
+ lab_t = transforms.ToTensor()(lab)
+ A = lab_t[[0], ...] / 50.0 - 1.0
+ B = lab_t[[1, 2], ...] / 110.0
+ return {"A": A, "B": B, "A_paths": path, "B_paths": path}
+
+ def __len__(self):
+ """Return the total number of images in the dataset."""
+ return len(self.AB_paths)
diff --git a/pix2pix_vgg/data/image_folder.py b/pix2pix_vgg/data/image_folder.py
new file mode 100644
index 0000000000000000000000000000000000000000..a596dd56c46496541ee737f181a0c6a905c7f957
--- /dev/null
+++ b/pix2pix_vgg/data/image_folder.py
@@ -0,0 +1,72 @@
+"""A modified image folder class
+
+We modify the official PyTorch image folder (https://github.com/pytorch/vision/blob/master/torchvision/datasets/folder.py)
+so that this class can load images from both current directory and its subdirectories.
+"""
+
+import torch.utils.data as data
+from pathlib import Path
+from PIL import Image
+
+IMG_EXTENSIONS = [
+ ".jpg",
+ ".JPG",
+ ".jpeg",
+ ".JPEG",
+ ".png",
+ ".PNG",
+ ".ppm",
+ ".PPM",
+ ".bmp",
+ ".BMP",
+ ".tif",
+ ".TIF",
+ ".tiff",
+ ".TIFF",
+]
+
+
+def is_image_file(filename):
+ return any(filename.endswith(extension) for extension in IMG_EXTENSIONS)
+
+
+def make_dataset(dir, max_dataset_size=float("inf")):
+ images = []
+ dir_path = Path(dir)
+ assert dir_path.is_dir(), f"{dir} is not a valid directory"
+
+ for path in sorted(dir_path.rglob("*")):
+ if path.is_file() and is_image_file(path.name):
+ images.append(str(path))
+ return images[: min(max_dataset_size, len(images))]
+
+
+def default_loader(path):
+ return Image.open(path).convert("RGB")
+
+
+class ImageFolder(data.Dataset):
+
+ def __init__(self, root, transform=None, return_paths=False, loader=default_loader):
+ imgs = make_dataset(root)
+ if len(imgs) == 0:
+ raise (RuntimeError("Found 0 images in: " + root + "\n" "Supported image extensions are: " + ",".join(IMG_EXTENSIONS)))
+
+ self.root = root
+ self.imgs = imgs
+ self.transform = transform
+ self.return_paths = return_paths
+ self.loader = loader
+
+ def __getitem__(self, index):
+ path = self.imgs[index]
+ img = self.loader(path)
+ if self.transform is not None:
+ img = self.transform(img)
+ if self.return_paths:
+ return img, path
+ else:
+ return img
+
+ def __len__(self):
+ return len(self.imgs)
diff --git a/pix2pix_vgg/data/single_dataset.py b/pix2pix_vgg/data/single_dataset.py
new file mode 100644
index 0000000000000000000000000000000000000000..f75afdf490d0ff566a956abc4e30f2f30f79a803
--- /dev/null
+++ b/pix2pix_vgg/data/single_dataset.py
@@ -0,0 +1,40 @@
+from data.base_dataset import BaseDataset, get_transform
+from data.image_folder import make_dataset
+from PIL import Image
+
+
+class SingleDataset(BaseDataset):
+ """This dataset class can load a set of images specified by the path --dataroot /path/to/data.
+
+ It can be used for generating CycleGAN results only for one side with the model option '-model test'.
+ """
+
+ def __init__(self, opt):
+ """Initialize this dataset class.
+
+ Parameters:
+ opt (Option class) -- stores all the experiment flags; needs to be a subclass of BaseOptions
+ """
+ BaseDataset.__init__(self, opt)
+ self.A_paths = sorted(make_dataset(opt.dataroot, opt.max_dataset_size))
+ input_nc = self.opt.output_nc if self.opt.direction == "BtoA" else self.opt.input_nc
+ self.transform = get_transform(opt, grayscale=(input_nc == 1))
+
+ def __getitem__(self, index):
+ """Return a data point and its metadata information.
+
+ Parameters:
+ index - - a random integer for data indexing
+
+ Returns a dictionary that contains A and A_paths
+ A(tensor) - - an image in one domain
+ A_paths(str) - - the path of the image
+ """
+ A_path = self.A_paths[index]
+ A_img = Image.open(A_path).convert("RGB")
+ A = self.transform(A_img)
+ return {"A": A, "A_paths": A_path}
+
+ def __len__(self):
+ """Return the total number of images in the dataset."""
+ return len(self.A_paths)
diff --git a/pix2pix_vgg/data/template_dataset.py b/pix2pix_vgg/data/template_dataset.py
new file mode 100644
index 0000000000000000000000000000000000000000..232f858086266bc98b10df6a8c90f35f2cb74fcb
--- /dev/null
+++ b/pix2pix_vgg/data/template_dataset.py
@@ -0,0 +1,78 @@
+"""Dataset class template
+
+This module provides a template for users to implement custom datasets.
+You can specify '--dataset_mode template' to use this dataset.
+The class name should be consistent with both the filename and its dataset_mode option.
+The filename should be _dataset.py
+The class name should be Dataset.py
+You need to implement the following functions:
+ -- : Add dataset-specific options and rewrite default values for existing options.
+ -- <__init__>: Initialize this dataset class.
+ -- <__getitem__>: Return a data point and its metadata information.
+ -- <__len__>: Return the number of images.
+"""
+
+from data.base_dataset import BaseDataset, get_transform
+
+# from data.image_folder import make_dataset
+# from PIL import Image
+
+
+class TemplateDataset(BaseDataset):
+ """A template dataset class for you to implement custom datasets."""
+
+ @staticmethod
+ def modify_commandline_options(parser, is_train):
+ """Add new dataset-specific options, and rewrite default values for existing options.
+
+ Parameters:
+ parser -- original option parser
+ is_train (bool) -- whether training phase or test phase. You can use this flag to add training-specific or test-specific options.
+
+ Returns:
+ the modified parser.
+ """
+ parser.add_argument("--new_dataset_option", type=float, default=1.0, help="new dataset option")
+ parser.set_defaults(max_dataset_size=10, new_dataset_option=2.0) # specify dataset-specific default values
+ return parser
+
+ def __init__(self, opt):
+ """Initialize this dataset class.
+
+ Parameters:
+ opt (Option class) -- stores all the experiment flags; needs to be a subclass of BaseOptions
+
+ A few things can be done here.
+ - save the options (have been done in BaseDataset)
+ - get image paths and meta information of the dataset.
+ - define the image transformation.
+ """
+ # save the option and dataset root
+ BaseDataset.__init__(self, opt)
+ # get the image paths of your dataset;
+ self.image_paths = [] # You can call sorted(make_dataset(self.root, opt.max_dataset_size)) to get all the image paths under the directory self.root
+ # define the default transform function. You can use ; You can also define your custom transform function
+ self.transform = get_transform(opt)
+
+ def __getitem__(self, index):
+ """Return a data point and its metadata information.
+
+ Parameters:
+ index -- a random integer for data indexing
+
+ Returns:
+ a dictionary of data with their names. It usually contains the data itself and its metadata information.
+
+ Step 1: get a random image path: e.g., path = self.image_paths[index]
+ Step 2: load your data from the disk: e.g., image = Image.open(path).convert('RGB').
+ Step 3: convert your data to a PyTorch tensor. You can use helpder functions such as self.transform. e.g., data = self.transform(image)
+ Step 4: return a data point as a dictionary.
+ """
+ path = "temp" # needs to be a string
+ data_A = None # needs to be a tensor
+ data_B = None # needs to be a tensor
+ return {"data_A": data_A, "data_B": data_B, "path": path}
+
+ def __len__(self):
+ """Return the total number of images."""
+ return len(self.image_paths)
diff --git a/pix2pix_vgg/data/unaligned_dataset.py b/pix2pix_vgg/data/unaligned_dataset.py
new file mode 100644
index 0000000000000000000000000000000000000000..3df7d1508bbf7a60f71d157a797f9032d903e36f
--- /dev/null
+++ b/pix2pix_vgg/data/unaligned_dataset.py
@@ -0,0 +1,71 @@
+import os
+from data.base_dataset import BaseDataset, get_transform
+from data.image_folder import make_dataset
+from PIL import Image
+import random
+
+
+class UnalignedDataset(BaseDataset):
+ """
+ This dataset class can load unaligned/unpaired datasets.
+
+ It requires two directories to host training images from domain A '/path/to/data/trainA'
+ and from domain B '/path/to/data/trainB' respectively.
+ You can train the model with the dataset flag '--dataroot /path/to/data'.
+ Similarly, you need to prepare two directories:
+ '/path/to/data/testA' and '/path/to/data/testB' during test time.
+ """
+
+ def __init__(self, opt):
+ """Initialize this dataset class.
+
+ Parameters:
+ opt (Option class) -- stores all the experiment flags; needs to be a subclass of BaseOptions
+ """
+ BaseDataset.__init__(self, opt)
+ self.dir_A = os.path.join(opt.dataroot, opt.phase + "A") # create a path '/path/to/data/trainA'
+ self.dir_B = os.path.join(opt.dataroot, opt.phase + "B") # create a path '/path/to/data/trainB'
+
+ self.A_paths = sorted(make_dataset(self.dir_A, opt.max_dataset_size)) # load images from '/path/to/data/trainA'
+ self.B_paths = sorted(make_dataset(self.dir_B, opt.max_dataset_size)) # load images from '/path/to/data/trainB'
+ self.A_size = len(self.A_paths) # get the size of dataset A
+ self.B_size = len(self.B_paths) # get the size of dataset B
+ btoA = self.opt.direction == "BtoA"
+ input_nc = self.opt.output_nc if btoA else self.opt.input_nc # get the number of channels of input image
+ output_nc = self.opt.input_nc if btoA else self.opt.output_nc # get the number of channels of output image
+ self.transform_A = get_transform(self.opt, grayscale=(input_nc == 1))
+ self.transform_B = get_transform(self.opt, grayscale=(output_nc == 1))
+
+ def __getitem__(self, index):
+ """Return a data point and its metadata information.
+
+ Parameters:
+ index (int) -- a random integer for data indexing
+
+ Returns a dictionary that contains A, B, A_paths and B_paths
+ A (tensor) -- an image in the input domain
+ B (tensor) -- its corresponding image in the target domain
+ A_paths (str) -- image paths
+ B_paths (str) -- image paths
+ """
+ A_path = self.A_paths[index % self.A_size] # make sure index is within then range
+ if self.opt.serial_batches: # make sure index is within then range
+ index_B = index % self.B_size
+ else: # randomize the index for domain B to avoid fixed pairs.
+ index_B = random.randint(0, self.B_size - 1)
+ B_path = self.B_paths[index_B]
+ A_img = Image.open(A_path).convert("RGB")
+ B_img = Image.open(B_path).convert("RGB")
+ # apply image transformation
+ A = self.transform_A(A_img)
+ B = self.transform_B(B_img)
+
+ return {"A": A, "B": B, "A_paths": A_path, "B_paths": B_path}
+
+ def __len__(self):
+ """Return the total number of images in the dataset.
+
+ As we have two datasets with potentially different number of images,
+ we take a maximum of
+ """
+ return max(self.A_size, self.B_size)
diff --git a/pix2pix_vgg/datasets/bibtex/cityscapes.tex b/pix2pix_vgg/datasets/bibtex/cityscapes.tex
new file mode 100644
index 0000000000000000000000000000000000000000..a87bdbf54fe9a5453fc8cf929299ef06d2f47691
--- /dev/null
+++ b/pix2pix_vgg/datasets/bibtex/cityscapes.tex
@@ -0,0 +1,6 @@
+@inproceedings{Cordts2016Cityscapes,
+title={The Cityscapes Dataset for Semantic Urban Scene Understanding},
+author={Cordts, Marius and Omran, Mohamed and Ramos, Sebastian and Rehfeld, Timo and Enzweiler, Markus and Benenson, Rodrigo and Franke, Uwe and Roth, Stefan and Schiele, Bernt},
+booktitle={Proc. of the IEEE Conference on Computer Vision and Pattern Recognition (CVPR)},
+year={2016}
+}
diff --git a/pix2pix_vgg/datasets/bibtex/facades.tex b/pix2pix_vgg/datasets/bibtex/facades.tex
new file mode 100644
index 0000000000000000000000000000000000000000..08b773e1188a9cfe8ce55b34616cead59c4d9243
--- /dev/null
+++ b/pix2pix_vgg/datasets/bibtex/facades.tex
@@ -0,0 +1,7 @@
+@INPROCEEDINGS{Tylecek13,
+ author = {Radim Tyle{\v c}ek, Radim {\v S}{\' a}ra},
+ title = {Spatial Pattern Templates for Recognition of Objects with Regular Structure},
+ booktitle = {Proc. GCPR},
+ year = {2013},
+ address = {Saarbrucken, Germany},
+}
diff --git a/pix2pix_vgg/datasets/bibtex/handbags.tex b/pix2pix_vgg/datasets/bibtex/handbags.tex
new file mode 100644
index 0000000000000000000000000000000000000000..b79710c7b5344b181a534e04696dd2e75c744ecf
--- /dev/null
+++ b/pix2pix_vgg/datasets/bibtex/handbags.tex
@@ -0,0 +1,13 @@
+@inproceedings{zhu2016generative,
+ title={Generative Visual Manipulation on the Natural Image Manifold},
+ author={Zhu, Jun-Yan and Kr{\"a}henb{\"u}hl, Philipp and Shechtman, Eli and Efros, Alexei A.},
+ booktitle={Proceedings of European Conference on Computer Vision (ECCV)},
+ year={2016}
+}
+
+@InProceedings{xie15hed,
+ author = {"Xie, Saining and Tu, Zhuowen"},
+ Title = {Holistically-Nested Edge Detection},
+ Booktitle = "Proceedings of IEEE International Conference on Computer Vision",
+ Year = {2015},
+}
diff --git a/pix2pix_vgg/datasets/bibtex/shoes.tex b/pix2pix_vgg/datasets/bibtex/shoes.tex
new file mode 100644
index 0000000000000000000000000000000000000000..e67e158b945e456b9613f0effb06784cd6682c20
--- /dev/null
+++ b/pix2pix_vgg/datasets/bibtex/shoes.tex
@@ -0,0 +1,14 @@
+@InProceedings{fine-grained,
+ author = {A. Yu and K. Grauman},
+ title = {{F}ine-{G}rained {V}isual {C}omparisons with {L}ocal {L}earning},
+ booktitle = {Computer Vision and Pattern Recognition (CVPR)},
+ month = {June},
+ year = {2014}
+}
+
+@InProceedings{xie15hed,
+ author = {"Xie, Saining and Tu, Zhuowen"},
+ Title = {Holistically-Nested Edge Detection},
+ Booktitle = "Proceedings of IEEE International Conference on Computer Vision",
+ Year = {2015},
+}
diff --git a/pix2pix_vgg/datasets/bibtex/transattr.tex b/pix2pix_vgg/datasets/bibtex/transattr.tex
new file mode 100644
index 0000000000000000000000000000000000000000..0585849961668d74e058b4a636f4ab0388723ba9
--- /dev/null
+++ b/pix2pix_vgg/datasets/bibtex/transattr.tex
@@ -0,0 +1,8 @@
+@article {Laffont14,
+ title = {Transient Attributes for High-Level Understanding and Editing of Outdoor Scenes},
+ author = {Pierre-Yves Laffont and Zhile Ren and Xiaofeng Tao and Chao Qian and James Hays},
+ journal = {ACM Transactions on Graphics (proceedings of SIGGRAPH)},
+ volume = {33},
+ number = {4},
+ year = {2014}
+}
diff --git a/pix2pix_vgg/datasets/combine_A_and_B.py b/pix2pix_vgg/datasets/combine_A_and_B.py
new file mode 100644
index 0000000000000000000000000000000000000000..c7f4cc5942b92324893f12ec0d4e2be0bd0f32f2
--- /dev/null
+++ b/pix2pix_vgg/datasets/combine_A_and_B.py
@@ -0,0 +1,68 @@
+import os
+import numpy as np
+import cv2
+import argparse
+from multiprocessing import Pool
+
+
+def image_write(path_A, path_B, path_AB):
+ im_A = cv2.imread(str(path_A), 1) # python2: cv2.CV_LOAD_IMAGE_COLOR; python3: cv2.IMREAD_COLOR
+ im_B = cv2.imread(str(path_B), 1) # python2: cv2.CV_LOAD_IMAGE_COLOR; python3: cv2.IMREAD_COLOR
+ im_AB = np.concatenate([im_A, im_B], 1)
+ cv2.imwrite(str(path_AB), im_AB)
+
+
+parser = argparse.ArgumentParser('create image pairs')
+parser.add_argument('--fold_A', dest='fold_A', help='input directory for image A', type=str, default='../dataset/50kshoes_edges')
+parser.add_argument('--fold_B', dest='fold_B', help='input directory for image B', type=str, default='../dataset/50kshoes_jpg')
+parser.add_argument('--fold_AB', dest='fold_AB', help='output directory', type=str, default='../dataset/test_AB')
+parser.add_argument('--num_imgs', dest='num_imgs', help='number of images', type=int, default=1000000)
+parser.add_argument('--use_AB', dest='use_AB', help='if true: (0001_A, 0001_B) to (0001_AB)', action='store_true')
+parser.add_argument('--no_multiprocessing', dest='no_multiprocessing', help='If used, chooses single CPU execution instead of parallel execution', action='store_true',default=False)
+args = parser.parse_args()
+
+for arg in vars(args):
+ print('[%s] = ' % arg, getattr(args, arg))
+
+fold_A = Path(args.fold_A)
+fold_B = Path(args.fold_B)
+fold_AB = Path(args.fold_AB)
+
+splits = [p.name for p in fold_A.iterdir() if p.is_dir()]
+
+if not args.no_multiprocessing:
+ pool=Pool()
+
+for sp in splits:
+ img_fold_A = fold_A / sp
+ img_fold_B = fold_B / sp
+ img_list = [p.name for p in img_fold_A.iterdir() if p.is_file()]
+ if args.use_AB:
+ img_list = [img_path for img_path in img_list if '_A.' in img_path]
+
+ num_imgs = min(args.num_imgs, len(img_list))
+ print('split = %s, use %d/%d images' % (sp, num_imgs, len(img_list)))
+ img_fold_AB = fold_AB / sp
+ img_fold_AB.mkdir(parents=True, exist_ok=True)
+ print('split = %s, number of images = %d' % (sp, num_imgs))
+ for n in range(num_imgs):
+ name_A = img_list[n]
+ path_A = img_fold_A / name_A
+ if args.use_AB:
+ name_B = name_A.replace('_A.', '_B.')
+ else:
+ name_B = name_A
+ path_B = img_fold_B / name_B
+ if path_A.is_file() and path_B.is_file():
+ name_AB = name_A
+ if args.use_AB:
+ name_AB = name_AB.replace('_A.', '.') # remove _A
+ path_AB = img_fold_AB / name_AB
+ if not args.no_multiprocessing:
+ pool.apply_async(image_write, args=(path_A, path_B, path_AB))
+ else:
+ image_write(path_A, path_B, path_AB)
+
+if not args.no_multiprocessing:
+ pool.close()
+ pool.join()
diff --git a/pix2pix_vgg/datasets/download_cyclegan_dataset.sh b/pix2pix_vgg/datasets/download_cyclegan_dataset.sh
new file mode 100644
index 0000000000000000000000000000000000000000..5d0b71a60c387ae34b125afad7f109680a75adc3
--- /dev/null
+++ b/pix2pix_vgg/datasets/download_cyclegan_dataset.sh
@@ -0,0 +1,21 @@
+FILE=$1
+
+if [[ $FILE != "ae_photos" && $FILE != "apple2orange" && $FILE != "summer2winter_yosemite" && $FILE != "horse2zebra" && $FILE != "monet2photo" && $FILE != "cezanne2photo" && $FILE != "ukiyoe2photo" && $FILE != "vangogh2photo" && $FILE != "maps" && $FILE != "cityscapes" && $FILE != "facades" && $FILE != "iphone2dslr_flower" && $FILE != "mini" && $FILE != "mini_pix2pix" && $FILE != "mini_colorization" ]]; then
+ echo "Available datasets are: apple2orange, summer2winter_yosemite, horse2zebra, monet2photo, cezanne2photo, ukiyoe2photo, vangogh2photo, maps, cityscapes, facades, iphone2dslr_flower, ae_photos"
+ exit 1
+fi
+
+if [[ $FILE == "cityscapes" ]]; then
+ echo "Due to license issue, we cannot provide the Cityscapes dataset from our repository. Please download the Cityscapes dataset from https://cityscapes-dataset.com, and use the script ./datasets/prepare_cityscapes_dataset.py."
+ echo "You need to download gtFine_trainvaltest.zip and leftImg8bit_trainvaltest.zip. For further instruction, please read ./datasets/prepare_cityscapes_dataset.py"
+ exit 1
+fi
+
+echo "Specified [$FILE]"
+URL=http://efrosgans.eecs.berkeley.edu/cyclegan/datasets/$FILE.zip
+ZIP_FILE=./datasets/$FILE.zip
+TARGET_DIR=./datasets/$FILE/
+wget -N $URL -O $ZIP_FILE
+mkdir $TARGET_DIR
+unzip $ZIP_FILE -d ./datasets/
+rm $ZIP_FILE
diff --git a/pix2pix_vgg/datasets/download_pix2pix_dataset.sh b/pix2pix_vgg/datasets/download_pix2pix_dataset.sh
new file mode 100644
index 0000000000000000000000000000000000000000..4cfbfb1fb00d4c3232790f8f098d7fb244ac7018
--- /dev/null
+++ b/pix2pix_vgg/datasets/download_pix2pix_dataset.sh
@@ -0,0 +1,22 @@
+FILE=$1
+
+if [[ $FILE != "cityscapes" && $FILE != "night2day" && $FILE != "edges2handbags" && $FILE != "edges2shoes" && $FILE != "facades" && $FILE != "maps" ]]; then
+ echo "Available datasets are cityscapes, night2day, edges2handbags, edges2shoes, facades, maps"
+ exit 1
+fi
+
+if [[ $FILE == "cityscapes" ]]; then
+ echo "Due to license issue, we cannot provide the Cityscapes dataset from our repository. Please download the Cityscapes dataset from https://cityscapes-dataset.com, and use the script ./datasets/prepare_cityscapes_dataset.py."
+ echo "You need to download gtFine_trainvaltest.zip and leftImg8bit_trainvaltest.zip. For further instruction, please read ./datasets/prepare_cityscapes_dataset.py"
+ exit 1
+fi
+
+echo "Specified [$FILE]"
+
+URL=http://efrosgans.eecs.berkeley.edu/pix2pix/datasets/$FILE.tar.gz
+TAR_FILE=./datasets/$FILE.tar.gz
+TARGET_DIR=./datasets/$FILE/
+wget -N $URL -O $TAR_FILE
+mkdir -p $TARGET_DIR
+tar -zxvf $TAR_FILE -C ./datasets/
+rm $TAR_FILE
diff --git a/pix2pix_vgg/datasets/make_dataset_aligned.py b/pix2pix_vgg/datasets/make_dataset_aligned.py
new file mode 100644
index 0000000000000000000000000000000000000000..739c767948c2f47bef16a88d552c25bdb12c6e3f
--- /dev/null
+++ b/pix2pix_vgg/datasets/make_dataset_aligned.py
@@ -0,0 +1,63 @@
+import os
+
+from PIL import Image
+
+
+def get_file_paths(folder):
+ image_file_paths = []
+ for root, dirs, filenames in os.walk(folder):
+ filenames = sorted(filenames)
+ for filename in filenames:
+ input_path = os.path.abspath(root)
+ file_path = os.path.join(input_path, filename)
+ if filename.endswith('.png') or filename.endswith('.jpg'):
+ image_file_paths.append(file_path)
+
+ break # prevent descending into subfolders
+ return image_file_paths
+
+
+def align_images(a_file_paths, b_file_paths, target_path):
+ if not os.path.exists(target_path):
+ os.makedirs(target_path)
+
+ for i in range(len(a_file_paths)):
+ img_a = Image.open(a_file_paths[i])
+ img_b = Image.open(b_file_paths[i])
+ assert(img_a.size == img_b.size)
+
+ aligned_image = Image.new("RGB", (img_a.size[0] * 2, img_a.size[1]))
+ aligned_image.paste(img_a, (0, 0))
+ aligned_image.paste(img_b, (img_a.size[0], 0))
+ aligned_image.save(os.path.join(target_path, '{:04d}.jpg'.format(i)))
+
+
+if __name__ == '__main__':
+ import argparse
+ parser = argparse.ArgumentParser()
+ parser.add_argument(
+ '--dataset-path',
+ dest='dataset_path',
+ help='Which folder to process (it should have subfolders testA, testB, trainA and trainB'
+ )
+ args = parser.parse_args()
+
+ dataset_folder = args.dataset_path
+ print(dataset_folder)
+
+ test_a_path = os.path.join(dataset_folder, 'testA')
+ test_b_path = os.path.join(dataset_folder, 'testB')
+ test_a_file_paths = get_file_paths(test_a_path)
+ test_b_file_paths = get_file_paths(test_b_path)
+ assert(len(test_a_file_paths) == len(test_b_file_paths))
+ test_path = os.path.join(dataset_folder, 'test')
+
+ train_a_path = os.path.join(dataset_folder, 'trainA')
+ train_b_path = os.path.join(dataset_folder, 'trainB')
+ train_a_file_paths = get_file_paths(train_a_path)
+ train_b_file_paths = get_file_paths(train_b_path)
+ assert(len(train_a_file_paths) == len(train_b_file_paths))
+ train_path = os.path.join(dataset_folder, 'train')
+
+ align_images(test_a_file_paths, test_b_file_paths, test_path)
+ align_images(train_a_file_paths, train_b_file_paths, train_path)
diff --git a/pix2pix_vgg/datasets/prepare_cityscapes_dataset.py b/pix2pix_vgg/datasets/prepare_cityscapes_dataset.py
new file mode 100644
index 0000000000000000000000000000000000000000..a5b2a20d004b17cf04c34f1d95b8f509aa16228f
--- /dev/null
+++ b/pix2pix_vgg/datasets/prepare_cityscapes_dataset.py
@@ -0,0 +1,99 @@
+import os
+import glob
+from PIL import Image
+
+help_msg = """
+The dataset can be downloaded from https://cityscapes-dataset.com.
+Please download the datasets [gtFine_trainvaltest.zip] and [leftImg8bit_trainvaltest.zip] and unzip them.
+gtFine contains the semantics segmentations. Use --gtFine_dir to specify the path to the unzipped gtFine_trainvaltest directory.
+leftImg8bit contains the dashcam photographs. Use --leftImg8bit_dir to specify the path to the unzipped leftImg8bit_trainvaltest directory.
+The processed images will be placed at --output_dir.
+
+Example usage:
+
+python prepare_cityscapes_dataset.py --gtFine_dir ./gtFine/ --leftImg8bit_dir ./leftImg8bit --output_dir ./datasets/cityscapes/
+"""
+
+def load_resized_img(path):
+ return Image.open(path).convert('RGB').resize((256, 256))
+
+def check_matching_pair(segmap_path, photo_path):
+ segmap_identifier = os.path.basename(segmap_path).replace('_gtFine_color', '')
+ photo_identifier = os.path.basename(photo_path).replace('_leftImg8bit', '')
+
+ assert segmap_identifier == photo_identifier, \
+ "[%s] and [%s] don't seem to be matching. Aborting." % (segmap_path, photo_path)
+
+
+def process_cityscapes(gtFine_dir, leftImg8bit_dir, output_dir, phase):
+ save_phase = 'test' if phase == 'val' else 'train'
+ savedir = os.path.join(output_dir, save_phase)
+ os.makedirs(savedir, exist_ok=True)
+ os.makedirs(savedir + 'A', exist_ok=True)
+ os.makedirs(savedir + 'B', exist_ok=True)
+ print("Directory structure prepared at %s" % output_dir)
+
+ segmap_expr = os.path.join(gtFine_dir, phase) + "/*/*_color.png"
+ segmap_paths = glob.glob(segmap_expr)
+ segmap_paths = sorted(segmap_paths)
+
+ photo_expr = os.path.join(leftImg8bit_dir, phase) + "/*/*_leftImg8bit.png"
+ photo_paths = glob.glob(photo_expr)
+ photo_paths = sorted(photo_paths)
+
+ assert len(segmap_paths) == len(photo_paths), \
+ "%d images that match [%s], and %d images that match [%s]. Aborting." % (len(segmap_paths), segmap_expr, len(photo_paths), photo_expr)
+
+ for i, (segmap_path, photo_path) in enumerate(zip(segmap_paths, photo_paths)):
+ check_matching_pair(segmap_path, photo_path)
+ segmap = load_resized_img(segmap_path)
+ photo = load_resized_img(photo_path)
+
+ # data for pix2pix where the two images are placed side-by-side
+ sidebyside = Image.new('RGB', (512, 256))
+ sidebyside.paste(segmap, (256, 0))
+ sidebyside.paste(photo, (0, 0))
+ savepath = os.path.join(savedir, "%d.jpg" % i)
+ sidebyside.save(savepath, format='JPEG', subsampling=0, quality=100)
+
+ # data for cyclegan where the two images are stored at two distinct directories
+ savepath = os.path.join(savedir + 'A', "%d_A.jpg" % i)
+ photo.save(savepath, format='JPEG', subsampling=0, quality=100)
+ savepath = os.path.join(savedir + 'B', "%d_B.jpg" % i)
+ segmap.save(savepath, format='JPEG', subsampling=0, quality=100)
+
+ if i % (len(segmap_paths) // 10) == 0:
+ print("%d / %d: last image saved at %s, " % (i, len(segmap_paths), savepath))
+
+
+
+
+
+
+
+
+
+
+if __name__ == '__main__':
+ import argparse
+ parser = argparse.ArgumentParser()
+ parser.add_argument('--gtFine_dir', type=str, required=True,
+ help='Path to the Cityscapes gtFine directory.')
+ parser.add_argument('--leftImg8bit_dir', type=str, required=True,
+ help='Path to the Cityscapes leftImg8bit_trainvaltest directory.')
+ parser.add_argument('--output_dir', type=str, required=True,
+ default='./datasets/cityscapes',
+ help='Directory the output images will be written to.')
+ opt = parser.parse_args()
+
+ print(help_msg)
+
+ print('Preparing Cityscapes Dataset for val phase')
+ process_cityscapes(opt.gtFine_dir, opt.leftImg8bit_dir, opt.output_dir, "val")
+ print('Preparing Cityscapes Dataset for train phase')
+ process_cityscapes(opt.gtFine_dir, opt.leftImg8bit_dir, opt.output_dir, "train")
+
+ print('Done')
+
+
+
diff --git a/pix2pix_vgg/docs/Dockerfile b/pix2pix_vgg/docs/Dockerfile
new file mode 100644
index 0000000000000000000000000000000000000000..0184be942f208affb7c3f7e95070666064d0e2a3
--- /dev/null
+++ b/pix2pix_vgg/docs/Dockerfile
@@ -0,0 +1,16 @@
+FROM nvidia/cuda:10.1-base
+
+#Nvidia Public GPG Key
+RUN apt-key adv --fetch-keys https://developer.download.nvidia.com/compute/cuda/repos/ubuntu1804/x86_64/3bf863cc.pub
+
+RUN apt update && apt install -y wget unzip curl bzip2 git
+RUN curl -LO http://repo.continuum.io/miniconda/Miniconda3-latest-Linux-x86_64.sh
+RUN bash Miniconda3-latest-Linux-x86_64.sh -p /miniconda -b
+RUN rm Miniconda3-latest-Linux-x86_64.sh
+ENV PATH=/miniconda/bin:${PATH}
+RUN conda update -y conda
+
+RUN conda install -y pytorch torchvision -c pytorch
+RUN mkdir /workspace/ && cd /workspace/ && git clone https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix.git && cd pytorch-CycleGAN-and-pix2pix && pip install -r requirements.txt
+
+WORKDIR /workspace
diff --git a/pix2pix_vgg/docs/README_es.md b/pix2pix_vgg/docs/README_es.md
new file mode 100644
index 0000000000000000000000000000000000000000..c4ad5d5c1e306eb3f4e5a1cf3620f41b9f21a4cd
--- /dev/null
+++ b/pix2pix_vgg/docs/README_es.md
@@ -0,0 +1,238 @@
+ +
+
+
+# CycleGAN y pix2pix en PyTorch
+
+Implementacion en PyTorch de Unpaired Image-to-Image Translation.
+
+Este codigo fue escrito por [Jun-Yan Zhu](https://github.com/junyanz) y [Taesung Park](https://github.com/taesung), y con ayuda de [Tongzhou Wang](https://ssnl.github.io/).
+
+Esta implementacion de PyTorch produce resultados comparables o mejores que nuestros original software de Torch. Si te gustaria producir los mismos resultados que en documento oficial, echa un vistazo al codigo original [CycleGAN Torch](https://github.com/junyanz/CycleGAN) y [pix2pix Torch](https://github.com/phillipi/pix2pix)
+
+**Aviso**: El software actual funciona correctamente en PyTorch 2.4+. Para soporte en PyTorch 0.1-0.3: [branch](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/tree/pytorch0.3.1).
+
+Puede encontrar información útil en [training/test tips](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/blob/master/docs/tips.md) y [preguntas frecuentes](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/blob/master/docs/qa.md). Para implementar modelos y conjuntos de datos personalizados, consulte nuestro [templates](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/blob/master/docs/README_es.md#modelo-y-dataset-personalizado). Para ayudar a los usuarios a comprender y adaptar mejor nuestra base de código, proporcionamos un [overview](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/blob/master/docs/overview.md) de la estructura de código de este repositorio.
+
+**CycleGAN: [Proyecto](https://junyanz.github.io/CycleGAN/) | [PDF](https://arxiv.org/pdf/1703.10593.pdf) | [Torch](https://github.com/junyanz/CycleGAN) |
+[Guia de Tensorflow Core](https://www.tensorflow.org/tutorials/generative/cyclegan) | [PyTorch Colab](https://colab.research.google.com/github/junyanz/pytorch-CycleGAN-and-pix2pix/blob/master/CycleGAN.ipynb)**
+
+
+
+**Pix2pix: [Proyeto](https://phillipi.github.io/pix2pix/) | [PDF](https://arxiv.org/pdf/1611.07004.pdf) | [Torch](https://github.com/phillipi/pix2pix) |
+[Guia de Tensorflow Core](https://www.tensorflow.org/tutorials/generative/cyclegan) | [PyTorch Colab](https://colab.research.google.com/github/junyanz/pytorch-CycleGAN-and-pix2pix/blob/master/pix2pix.ipynb)**
+
+
+
+
+**[EdgesCats Demo](https://affinelayer.com/pixsrv/) | [pix2pix-tensorflow](https://github.com/affinelayer/pix2pix-tensorflow) | por [Christopher Hesse](https://twitter.com/christophrhesse)**
+
+ +
+Si usa este código para su investigación, cite:
+
+Unpaired Image-to-Image Translation usando Cycle-Consistent Adversarial Networks.
+[Jun-Yan Zhu](https://www.cs.cmu.edu/~junyanz/)\*, [Taesung Park](https://taesung.me/)\*, [Phillip Isola](https://people.eecs.berkeley.edu/~isola/), [Alexei A. Efros](https://people.eecs.berkeley.edu/~efros). In ICCV 2017. (* contribucion igualitaria) [[Bibtex]](https://junyanz.github.io/CycleGAN/CycleGAN.txt)
+
+
+Image-to-Image Translation usando Conditional Adversarial Networks.
+[Phillip Isola](https://people.eecs.berkeley.edu/~isola), [Jun-Yan Zhu](https://www.cs.cmu.edu/~junyanz/), [Tinghui Zhou](https://people.eecs.berkeley.edu/~tinghuiz), [Alexei A. Efros](https://people.eecs.berkeley.edu/~efros). In CVPR 2017. [[Bibtex]](https://www.cs.cmu.edu/~junyanz/projects/pix2pix/pix2pix.bib)
+
+## Charlas y curso
+Presentacion en PowerPoint de Pix2pix: [keynote](http://efrosgans.eecs.berkeley.edu/CVPR18_slides/pix2pix.key) | [pdf](http://efrosgans.eecs.berkeley.edu/CVPR18_slides/pix2pix.pdf),
+Presentacion en PowerPoint de CycleGAN: [pptx](http://efrosgans.eecs.berkeley.edu/CVPR18_slides/CycleGAN.pptx) | [pdf](http://efrosgans.eecs.berkeley.edu/CVPR18_slides/CycleGAN.pdf)
+
+Asignación del curso CycleGAN [codigo](http://www.cs.toronto.edu/~rgrosse/courses/csc321_2018/assignments/a4-code.zip) y [handout](http://www.cs.toronto.edu/~rgrosse/courses/csc321_2018/assignments/a4-handout.pdf) diseñado por el Prof. [Roger Grosse](http://www.cs.toronto.edu/~rgrosse/) for [CSC321](http://www.cs.toronto.edu/~rgrosse/courses/csc321_2018/) "Intro to Neural Networks and Machine Learning" en la universidad de Toronto. Póngase en contacto con el instructor si desea adoptarlo en su curso.
+
+## Colab Notebook
+TensorFlow Core CycleGAN Tutorial: [Google Colab](https://colab.research.google.com/github/tensorflow/docs/blob/master/site/en/tutorials/generative/cyclegan.ipynb) | [Codigo](https://github.com/tensorflow/docs/blob/master/site/en/tutorials/generative/cyclegan.ipynb)
+
+Guia de TensorFlow Core pix2pix : [Google Colab](https://colab.research.google.com/github/tensorflow/docs/blob/master/site/en/tutorials/generative/pix2pix.ipynb) | [Codigo](https://github.com/tensorflow/docs/blob/master/site/en/tutorials/generative/pix2pix.ipynb)
+
+PyTorch Colab notebook: [CycleGAN](https://colab.research.google.com/github/junyanz/pytorch-CycleGAN-and-pix2pix/blob/master/CycleGAN.ipynb) y [pix2pix](https://colab.research.google.com/github/junyanz/pytorch-CycleGAN-and-pix2pix/blob/master/pix2pix.ipynb)
+
+## Otras implementaciones
+### CycleGAN
+ [Tensorflow] (por Harry Yang),
+[Tensorflow] (por Archit Rathore),
+[Tensorflow] (por Van Huy),
+[Tensorflow] (por Xiaowei Hu),
+ [Tensorflow-simple] (por Zhenliang He),
+ [TensorLayer] (por luoxier),
+[Chainer] (por Yanghua Jin),
+[Minimal PyTorch] (por yunjey),
+[Mxnet] (por Ldpe2G),
+[lasagne/Keras] (por tjwei),
+[Keras] (por Simon Karlsson)
+
+
+
+### pix2pix
+ [Tensorflow] (por Christopher Hesse),
+[Tensorflow] (por Eyyüb Sariu),
+ [Tensorflow (face2face)] (por Dat Tran),
+ [Tensorflow (film)] (por Arthur Juliani),
+[Tensorflow (zi2zi)] (por Yuchen Tian),
+[Chainer] (por mattya),
+[tf/torch/keras/lasagne] (por tjwei),
+[Pytorch] (por taey16)
+
+
+
+## Requerimientos
+- Linux o macOS
+- Python 3
+- CPU o NVIDIA GPU usando CUDA CuDNN
+
+## Inicio
+### Instalación
+
+- Clone este repositorio:
+```bash
+git clone https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix
+cd pytorch-CycleGAN-and-pix2pix
+```
+
+- Instale [PyTorch](http://pytorch.org) 0.4+ y sus otras dependencias (e.g., torchvision, [visdom](https://github.com/facebookresearch/visdom) y [dominate](https://github.com/Knio/dominate)).
+ - Para uso de pip, por favor escriba el comando `pip install -r requirements.txt`.
+ - Para uso de Conda, proporcionamos un script de instalación `./scripts/conda_deps.sh`. De forma alterna, puede crear un nuevo entorno Conda usando `conda env create -f environment.yml`.
+ - Para uso de Docker, Proporcionamos la imagen Docker y el archivo Docker preconstruidos. Por favor, consulte nuestra página
+ [Docker](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/blob/master/docs/docker.md).
+
+### CycleGAN entreanimiento/test
+- Descargar el dataset de CycleGAN (e.g. maps):
+```bash
+bash ./datasets/download_cyclegan_dataset.sh maps
+```
+- Para ver los resultados del entrenamiento y las gráficas de pérdidas, `python -m visdom.server` y haga clic en la URL
+ http://localhost:8097.
+- Entrenar el modelo:
+```bash
+#!./scripts/train_cyclegan.sh
+python train.py --dataroot ./datasets/maps --name maps_cyclegan --model cycle_gan
+```
+Para ver más resultados intermedios, consulte `./checkpoints/maps_cyclegan/web/index.html`.
+- Pruebe el modelo:
+```bash
+#!./scripts/test_cyclegan.sh
+python test.py --dataroot ./datasets/maps --name maps_cyclegan --model cycle_gan
+```
+-Los resultados de la prueba se guardarán en un archivo html aquí: `./results/maps_cyclegan/latest_test/index.html`.
+
+### pix2pix entrenamiento/test
+- Descargue el dataset de pix2pix (e.g.[facades](http://cmp.felk.cvut.cz/~tylecr1/facade/)):
+```bash
+bash ./datasets/download_pix2pix_dataset.sh facades
+```
+- Para ver los resultados del entrenamiento y las gráficas de pérdidas `python -m visdom.server`, haga clic en la URL http://localhost:8097.
+- Para entrenar el modelo:
+```bash
+#!./scripts/train_pix2pix.sh
+python train.py --dataroot ./datasets/facades --name facades_pix2pix --model pix2pix --direction BtoA
+```
+Para ver más resultados intermedios, consulte `./checkpoints/facades_pix2pix/web/index.html`.
+
+- Pruebe el modelo (`bash ./scripts/test_pix2pix.sh`):
+```bash
+#!./scripts/test_pix2pix.sh
+python test.py --dataroot ./datasets/facades --name facades_pix2pix --model pix2pix --direction BtoA
+```
+- Los resultados de la prueba se guardarán en un archivo html aquí: `./results/facades_pix2pix/test_latest/index.html`. Puede encontrar más scripts en `scripts` directory.
+- Para entrenar y probar modelos de colorización basados en pix2pix, agregue la linea `--model colorization` y `--dataset_mode colorization`. Para más detalles de nuestro entrenamiento [tips](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/blob/master/docs/tips.md#notes-on-colorization).
+
+### Aplicar un modelo pre-entrenado (CycleGAN)
+- Puedes descargar un modelo previamente entrenado (e.g. horse2zebra) con el siguiente script:
+```bash
+bash ./scripts/download_cyclegan_model.sh horse2zebra
+```
+- El modelo pre-entrenado se guarda en `./checkpoints/{name}_pretrained/latest_net_G.pth`. Revise [aqui](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/blob/master/scripts/download_cyclegan_model.sh#L3) para todos los modelos CycleGAN disponibles.
+
+- Para probar el modelo, también debe descargar el dataset horse2zebra:
+```bash
+bash ./datasets/download_cyclegan_dataset.sh horse2zebra
+```
+
+- Luego genere los resultados usando:
+```bash
+python test.py --dataroot datasets/horse2zebra/testA --name horse2zebra_pretrained --model test --no_dropout
+```
+- La opcion `--model test` ise usa para generar resultados de CycleGAN de un solo lado. Esta opción configurará automáticamente
+ `--dataset_mode single`, carga solo las imágenes de un conjunto. Por el contrario, el uso de `--model cycle_gan` requiere cargar y generar resultados en ambas direcciones, lo que a veces es innecesario. Los resultados se guardarán en `./results/`. Use `--results_dir {directory_path_to_save_result}` para especificar el directorio de resultados.
+
+- Para sus propios experimentos, es posible que desee especificar `--netG`, `--norm`, `--no_dropout` para que coincida con la arquitectura del generador del modelo entrenado.
+
+### Aplicar un modelo pre-entrenado (pix2pix)
+Descargue un modelo pre-entrenado con `./scripts/download_pix2pix_model.sh`.
+
+- Revise [aqui](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/blob/master/scripts/download_pix2pix_model.sh#L3) para todos los modelos pix2pix disponibles. Por ejemplo, si desea descargar el modelo label2photo en el dataset:
+```bash
+bash ./scripts/download_pix2pix_model.sh facades_label2photo
+```
+- Descarga el dataset facades de pix2pix:
+```bash
+bash ./datasets/download_pix2pix_dataset.sh facades
+```
+- Luego genere los resultados usando:
+```bash
+python test.py --dataroot ./datasets/facades/ --direction BtoA --model pix2pix --name facades_label2photo_pretrained
+```
+- Tenga en cuenta que `--direction BtoA` como Facades dataset's, son direcciones A o B para etiquetado de fotos.
+
+- Si desea aplicar un modelo previamente entrenado a una colección de imágenes de entrada (en lugar de pares de imágenes), use la opcion `--model test`. Vea `./scripts/test_single.sh` obre cómo aplicar un modelo a Facade label maps (almacenados en el directorio `facades/testB`).
+
+- Vea una lista de los modelos disponibles actualmente en `./scripts/download_pix2pix_model.sh`
+
+## [Docker](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/blob/master/docs/docker.md)
+Proporcionamos la imagen Docker y el archivo Docker preconstruidos que pueden ejecutar este repositorio de código. Ver [docker](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/blob/master/docs/docker.md).
+
+## [Datasets](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/blob/master/docs/datasets.md)
+Descargue los conjuntos de datos pix2pix / CycleGAN y cree sus propios conjuntos de datos.
+
+## [Entretanimiento/Test Tips](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/blob/master/docs/tips.md)
+Las mejores prácticas para entrenar y probar sus modelos.
+
+## [Preguntas frecuentes](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/blob/master/docs/qa.md)
+Antes de publicar una nueva pregunta, primero mire las preguntas y respuestas anteriores y los problemas existentes de GitHub.
+
+## Modelo y Dataset personalizado
+Si planea implementar modelos y conjuntos de datos personalizados para sus nuevas aplicaciones, proporcionamos un conjunto de datos [template](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/blob/master/data/template_dataset.py) y un modelo [template](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/blob/master/models/template_model.py) como punto de partida.
+
+
+## [Estructura de codigo](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/blob/master/docs/overview.md)
+Para ayudar a los usuarios a comprender mejor y usar nuestro código, presentamos brevemente la funcionalidad e implementación de cada paquete y cada módulo.
+
+## Solicitud de Pull
+Siempre puede contribuir a este repositorio enviando un [pull request](https://help.github.com/articles/about-pull-requests/).
+Por favor ejecute `flake8 --ignore E501 .` y `python ./scripts/test_before_push.py` antes de realizar un Pull en el código, asegure de también actualizar la estructura del código [overview](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/blob/master/docs/overview.md) en consecuencia si agrega o elimina archivos.
+
+
+## Citación
+Si utiliza este código para su investigación, cite nuestros documentos.
+```
+@inproceedings{CycleGAN2017,
+ title={Unpaired Image-to-Image Translation using Cycle-Consistent Adversarial Networkss},
+ author={Zhu, Jun-Yan and Park, Taesung and Isola, Phillip and Efros, Alexei A},
+ booktitle={Computer Vision (ICCV), 2017 IEEE International Conference on},
+ year={2017}
+}
+
+
+@inproceedings{isola2017image,
+ title={Image-to-Image Translation with Conditional Adversarial Networks},
+ author={Isola, Phillip and Zhu, Jun-Yan and Zhou, Tinghui and Efros, Alexei A},
+ booktitle={Computer Vision and Pattern Recognition (CVPR), 2017 IEEE Conference on},
+ year={2017}
+}
+```
+
+## Proyectos relacionados
+**[CycleGAN-Torch](https://github.com/junyanz/CycleGAN) |
+[pix2pix-Torch](https://github.com/phillipi/pix2pix) | [pix2pixHD](https://github.com/NVIDIA/pix2pixHD)|
+[BicycleGAN](https://github.com/junyanz/BicycleGAN) | [vid2vid](https://tcwang0509.github.io/vid2vid/) | [SPADE/GauGAN](https://github.com/NVlabs/SPADE)**
+**[iGAN](https://github.com/junyanz/iGAN) | [GAN Dissection](https://github.com/CSAILVision/GANDissect) | [GAN Paint](http://ganpaint.io/)**
+
+## Cat Paper Collection
+Si amas a los gatos y te encanta leer gráficos geniales, computer vision y documentos de aprendizaje, echa un vistazo a Cat Paper [Collection](https://github.com/junyanz/CatPapers).
+
+## Agradecimientos
+Nuestro código fue inspirado en [pytorch-DCGAN](https://github.com/pytorch/examples/tree/master/dcgan).
diff --git a/pix2pix_vgg/docs/datasets.md b/pix2pix_vgg/docs/datasets.md
new file mode 100644
index 0000000000000000000000000000000000000000..b53c7db4b6db1800c735e2e5bec93ebe73cc9a30
--- /dev/null
+++ b/pix2pix_vgg/docs/datasets.md
@@ -0,0 +1,44 @@
+
+
+### CycleGAN Datasets
+Download the CycleGAN datasets using the following script. Some of the datasets are collected by other researchers. Please cite their papers if you use the data.
+```bash
+bash ./datasets/download_cyclegan_dataset.sh dataset_name
+```
+- `facades`: 400 images from the [CMP Facades dataset](http://cmp.felk.cvut.cz/~tylecr1/facade). [[Citation](../datasets/bibtex/facades.tex)]
+- `cityscapes`: 2975 images from the [Cityscapes training set](https://www.cityscapes-dataset.com). [[Citation](../datasets/bibtex/cityscapes.tex)]. Note: Due to license issue, we cannot directly provide the Cityscapes dataset. Please download the Cityscapes dataset from [https://cityscapes-dataset.com](https://cityscapes-dataset.com) and use the script `./datasets/prepare_cityscapes_dataset.py`.
+- `maps`: 1096 training images scraped from Google Maps.
+- `horse2zebra`: 939 horse images and 1177 zebra images downloaded from [ImageNet](http://www.image-net.org) using keywords `wild horse` and `zebra`
+- `apple2orange`: 996 apple images and 1020 orange images downloaded from [ImageNet](http://www.image-net.org) using keywords `apple` and `navel orange`.
+- `summer2winter_yosemite`: 1273 summer Yosemite images and 854 winter Yosemite images were downloaded using Flickr API. See more details in our paper.
+- `monet2photo`, `vangogh2photo`, `ukiyoe2photo`, `cezanne2photo`: The art images were downloaded from [Wikiart](https://www.wikiart.org/). The real photos are downloaded from Flickr using the combination of the tags *landscape* and *landscapephotography*. The training set size of each class is Monet:1074, Cezanne:584, Van Gogh:401, Ukiyo-e:1433, Photographs:6853.
+- `iphone2dslr_flower`: both classes of images were downlaoded from Flickr. The training set size of each class is iPhone:1813, DSLR:3316. See more details in our paper.
+
+To train a model on your own datasets, you need to create a data folder with two subdirectories `trainA` and `trainB` that contain images from domain A and B. You can test your model on your training set by setting `--phase train` in `test.py`. You can also create subdirectories `testA` and `testB` if you have test data.
+
+You should **not** expect our method to work on just any random combination of input and output datasets (e.g. `cats<->keyboards`). From our experiments, we find it works better if two datasets share similar visual content. For example, `landscape painting<->landscape photographs` works much better than `portrait painting <-> landscape photographs`. `zebras<->horses` achieves compelling results while `cats<->dogs` completely fails.
+
+### pix2pix datasets
+Download the pix2pix datasets using the following script. Some of the datasets are collected by other researchers. Please cite their papers if you use the data.
+```bash
+bash ./datasets/download_pix2pix_dataset.sh dataset_name
+```
+- `facades`: 400 images from [CMP Facades dataset](http://cmp.felk.cvut.cz/~tylecr1/facade). [[Citation](../datasets/bibtex/facades.tex)]
+- `cityscapes`: 2975 images from the [Cityscapes training set](https://www.cityscapes-dataset.com). [[Citation](../datasets/bibtex/cityscapes.tex)]
+- `maps`: 1096 training images scraped from Google Maps
+- `edges2shoes`: 50k training images from [UT Zappos50K dataset](http://vision.cs.utexas.edu/projects/finegrained/utzap50k). Edges are computed by [HED](https://github.com/s9xie/hed) edge detector + post-processing. [[Citation](datasets/bibtex/shoes.tex)]
+- `edges2handbags`: 137K Amazon Handbag images from [iGAN project](https://github.com/junyanz/iGAN). Edges are computed by [HED](https://github.com/s9xie/hed) edge detector + post-processing. [[Citation](datasets/bibtex/handbags.tex)]
+- `night2day`: around 20K natural scene images from [Transient Attributes dataset](http://transattr.cs.brown.edu/) [[Citation](datasets/bibtex/transattr.tex)]. To train a `day2night` pix2pix model, you need to add `--direction BtoA`.
+
+We provide a python script to generate pix2pix training data in the form of pairs of images {A,B}, where A and B are two different depictions of the same underlying scene. For example, these might be pairs {label map, photo} or {bw image, color image}. Then we can learn to translate A to B or B to A:
+
+Create folder `/path/to/data` with subfolders `A` and `B`. `A` and `B` should each have their own subfolders `train`, `val`, `test`, etc. In `/path/to/data/A/train`, put training images in style A. In `/path/to/data/B/train`, put the corresponding images in style B. Repeat same for other data splits (`val`, `test`, etc).
+
+Corresponding images in a pair {A,B} must be the same size and have the same filename, e.g., `/path/to/data/A/train/1.jpg` is considered to correspond to `/path/to/data/B/train/1.jpg`.
+
+Once the data is formatted this way, call:
+```bash
+python datasets/combine_A_and_B.py --fold_A /path/to/data/A --fold_B /path/to/data/B --fold_AB /path/to/data
+```
+
+This will combine each pair of images (A,B) into a single image file, ready for training.
diff --git a/pix2pix_vgg/docs/docker.md b/pix2pix_vgg/docs/docker.md
new file mode 100644
index 0000000000000000000000000000000000000000..74043e3a37e57fbf47bc37a4d489ca457ffd7858
--- /dev/null
+++ b/pix2pix_vgg/docs/docker.md
@@ -0,0 +1,38 @@
+# Docker image with pytorch-CycleGAN-and-pix2pix
+
+We provide both Dockerfile and pre-built Docker container that can run this code repo.
+
+## Prerequisite
+
+- Install [docker-ce](https://docs.docker.com/install/linux/docker-ce/ubuntu/)
+- Install [nvidia-docker](https://github.com/NVIDIA/nvidia-docker#quickstart)
+
+## Running pre-built Dockerfile
+
+- Pull the pre-built docker file
+
+```bash
+docker pull taesungp/pytorch-cyclegan-and-pix2pix
+```
+
+- Start an interactive docker session. `-p 8097:8097` option is needed if you want to run `visdom` server on the Docker container.
+
+```bash
+nvidia-docker run -it -p 8097:8097 taesungp/pytorch-cyclegan-and-pix2pix
+```
+
+- Now you are in the Docker environment. Go to our code repo and start running things.
+```bash
+cd /workspace/pytorch-CycleGAN-and-pix2pix
+bash datasets/download_pix2pix_dataset.sh facades
+python -m visdom.server &
+bash scripts/train_pix2pix.sh
+```
+
+## Running with Dockerfile
+
+We also posted the [Dockerfile](Dockerfile). To generate the pre-built file, download the Dockerfile in this directory and run
+```bash
+docker build -t [target_tag] .
+```
+in the directory that contains the Dockerfile.
diff --git a/pix2pix_vgg/docs/overview.md b/pix2pix_vgg/docs/overview.md
new file mode 100644
index 0000000000000000000000000000000000000000..4ce98412807f378401330af5372fe726ea5070c9
--- /dev/null
+++ b/pix2pix_vgg/docs/overview.md
@@ -0,0 +1,45 @@
+## Overview of Code Structure
+To help users better understand and use our codebase, we briefly overview the functionality and implementation of each package and each module. Please see the documentation in each file for more details. If you have questions, you may find useful information in [training/test tips](tips.md) and [frequently asked questions](qa.md).
+
+[train.py](../train.py) is a general-purpose training script. It works for various models (with option `--model`: e.g., `pix2pix`, `cyclegan`, `colorization`) and different datasets (with option `--dataset_mode`: e.g., `aligned`, `unaligned`, `single`, `colorization`). See the main [README](.../README.md) and [training/test tips](tips.md) for more details.
+
+[test.py](../test.py) is a general-purpose test script. Once you have trained your model with `train.py`, you can use this script to test the model. It will load a saved model from `--checkpoints_dir` and save the results to `--results_dir`. See the main [README](.../README.md) and [training/test tips](tips.md) for more details.
+
+
+[data](../data) directory contains all the modules related to data loading and preprocessing. To add a custom dataset class called `dummy`, you need to add a file called `dummy_dataset.py` and define a subclass `DummyDataset` inherited from `BaseDataset`. You need to implement four functions: `__init__` (initialize the class, you need to first call `BaseDataset.__init__(self, opt)`), `__len__` (return the size of dataset), `__getitem__` (get a data point), and optionally `modify_commandline_options` (add dataset-specific options and set default options). Now you can use the dataset class by specifying flag `--dataset_mode dummy`. See our template dataset [class](../data/template_dataset.py) for an example. Below we explain each file in details.
+
+* [\_\_init\_\_.py](../data/__init__.py) implements the interface between this package and training and test scripts. `train.py` and `test.py` call `from data import create_dataset` and `dataset = create_dataset(opt)` to create a dataset given the option `opt`.
+* [base_dataset.py](../data/base_dataset.py) implements an abstract base class ([ABC](https://docs.python.org/3/library/abc.html)) for datasets. It also includes common transformation functions (e.g., `get_transform`, `__scale_width`), which can be later used in subclasses.
+* [image_folder.py](../data/image_folder.py) implements an image folder class. We modify the official PyTorch image folder [code](https://github.com/pytorch/vision/blob/master/torchvision/datasets/folder.py) so that this class can load images from both the current directory and its subdirectories.
+* [template_dataset.py](../data/template_dataset.py) provides a dataset template with detailed documentation. Check out this file if you plan to implement your own dataset.
+* [aligned_dataset.py](../data/aligned_dataset.py) includes a dataset class that can load image pairs. It assumes a single image directory `/path/to/data/train`, which contains image pairs in the form of {A,B}. See [here](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/blob/master/docs/tips.md#prepare-your-own-datasets-for-pix2pix) on how to prepare aligned datasets. During test time, you need to prepare a directory `/path/to/data/test` as test data.
+* [unaligned_dataset.py](../data/unaligned_dataset.py) includes a dataset class that can load unaligned/unpaired datasets. It assumes that two directories to host training images from domain A `/path/to/data/trainA` and from domain B `/path/to/data/trainB` respectively. Then you can train the model with the dataset flag `--dataroot /path/to/data`. Similarly, you need to prepare two directories `/path/to/data/testA` and `/path/to/data/testB` during test time.
+* [single_dataset.py](../data/single_dataset.py) includes a dataset class that can load a set of single images specified by the path `--dataroot /path/to/data`. It can be used for generating CycleGAN results only for one side with the model option `-model test`.
+* [colorization_dataset.py](../data/colorization_dataset.py) implements a dataset class that can load a set of nature images in RGB, and convert RGB format into (L, ab) pairs in [Lab](https://en.wikipedia.org/wiki/CIELAB_color_space) color space. It is required by pix2pix-based colorization model (`--model colorization`).
+
+
+[models](../models) directory contains modules related to objective functions, optimizations, and network architectures. To add a custom model class called `dummy`, you need to add a file called `dummy_model.py` and define a subclass `DummyModel` inherited from `BaseModel`. You need to implement four functions: `__init__` (initialize the class; you need to first call `BaseModel.__init__(self, opt)`), `set_input` (unpack data from dataset and apply preprocessing), `forward` (generate intermediate results), `optimize_parameters` (calculate loss, gradients, and update network weights), and optionally `modify_commandline_options` (add model-specific options and set default options). Now you can use the model class by specifying flag `--model dummy`. See our template model [class](../models/template_model.py) for an example. Below we explain each file in details.
+
+* [\_\_init\_\_.py](../models/__init__.py) implements the interface between this package and training and test scripts. `train.py` and `test.py` call `from models import create_model` and `model = create_model(opt)` to create a model given the option `opt`. You also need to call `model.setup(opt)` to properly initialize the model.
+* [base_model.py](../models/base_model.py) implements an abstract base class ([ABC](https://docs.python.org/3/library/abc.html)) for models. It also includes commonly used helper functions (e.g., `setup`, `test`, `update_learning_rate`, `save_networks`, `load_networks`), which can be later used in subclasses.
+* [template_model.py](../models/template_model.py) provides a model template with detailed documentation. Check out this file if you plan to implement your own model.
+* [pix2pix_model.py](../models/pix2pix_model.py) implements the pix2pix [model](https://phillipi.github.io/pix2pix/), for learning a mapping from input images to output images given paired data. The model training requires `--dataset_mode aligned` dataset. By default, it uses a `--netG unet256` [U-Net](https://arxiv.org/pdf/1505.04597.pdf) generator, a `--netD basic` discriminator (PatchGAN), and a `--gan_mode vanilla` GAN loss (standard cross-entropy objective).
+* [colorization_model.py](../models/colorization_model.py) implements a subclass of `Pix2PixModel` for image colorization (black & white image to colorful image). The model training requires `-dataset_model colorization` dataset. It trains a pix2pix model, mapping from L channel to ab channels in [Lab](https://en.wikipedia.org/wiki/CIELAB_color_space) color space. By default, the `colorization` dataset will automatically set `--input_nc 1` and `--output_nc 2`.
+* [cycle_gan_model.py](../models/cycle_gan_model.py) implements the CycleGAN [model](https://junyanz.github.io/CycleGAN/), for learning image-to-image translation without paired data. The model training requires `--dataset_mode unaligned` dataset. By default, it uses a `--netG resnet_9blocks` ResNet generator, a `--netD basic` discriminator (PatchGAN introduced by pix2pix), and a least-square GANs [objective](https://arxiv.org/abs/1611.04076) (`--gan_mode lsgan`).
+* [networks.py](../models/networks.py) module implements network architectures (both generators and discriminators), as well as normalization layers, initialization methods, optimization scheduler (i.e., learning rate policy), and GAN objective function (`vanilla`, `lsgan`, `wgangp`).
+* [test_model.py](../models/test_model.py) implements a model that can be used to generate CycleGAN results for only one direction. This model will automatically set `--dataset_mode single`, which only loads the images from one set. See the test [instruction](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix#apply-a-pre-trained-model-cyclegan) for more details.
+
+[options](../options) directory includes our option modules: training options, test options, and basic options (used in both training and test). `TrainOptions` and `TestOptions` are both subclasses of `BaseOptions`. They will reuse the options defined in `BaseOptions`.
+* [\_\_init\_\_.py](../options/__init__.py) is required to make Python treat the directory `options` as containing packages,
+* [base_options.py](../options/base_options.py) includes options that are used in both training and test. It also implements a few helper functions such as parsing, printing, and saving the options. It also gathers additional options defined in `modify_commandline_options` functions in both dataset class and model class.
+* [train_options.py](../options/train_options.py) includes options that are only used during training time.
+* [test_options.py](../options/test_options.py) includes options that are only used during test time.
+
+
+[util](../util) directory includes a miscellaneous collection of useful helper functions.
+ * [\_\_init\_\_.py](../util/__init__.py) is required to make Python treat the directory `util` as containing packages,
+ * [get_data.py](../util/get_data.py) provides a Python script for downloading CycleGAN and pix2pix datasets. Alternatively, You can also use bash scripts such as [download_pix2pix_model.sh](../scripts/download_pix2pix_model.sh) and [download_cyclegan_model.sh](../scripts/download_cyclegan_model.sh).
+ * [html.py](../util/html.py) implements a module that saves images into a single HTML file. It consists of functions such as `add_header` (add a text header to the HTML file), `add_images` (add a row of images to the HTML file), `save` (save the HTML to the disk). It is based on Python library `dominate`, a Python library for creating and manipulating HTML documents using a DOM API.
+ * [image_pool.py](../util/image_pool.py) implements an image buffer that stores previously generated images. This buffer enables us to update discriminators using a history of generated images rather than the ones produced by the latest generators. The original idea was discussed in this [paper](http://openaccess.thecvf.com/content_cvpr_2017/papers/Shrivastava_Learning_From_Simulated_CVPR_2017_paper.pdf). The size of the buffer is controlled by the flag `--pool_size`.
+ * [visualizer.py](../util/visualizer.py) includes several functions that can display/save images and print/save logging information. It uses Weights & Biases for logging and a Python library `dominate` (wrapped in `HTML`) for creating HTML files with images.
+ * [util.py](../util/util.py) consists of simple helper functions such as `tensor2im` (convert a tensor array to a numpy image array), `diagnose_network` (calculate and print the mean of average absolute value of gradients), and `mkdirs` (create multiple directories).
diff --git a/pix2pix_vgg/docs/qa.md b/pix2pix_vgg/docs/qa.md
new file mode 100644
index 0000000000000000000000000000000000000000..dcb67d808d0b17b5443b5556b79630f468c3b1fa
--- /dev/null
+++ b/pix2pix_vgg/docs/qa.md
@@ -0,0 +1,175 @@
+## Frequently Asked Questions
+
+Before you post a new question, please first look at the following Q & A and existing GitHub issues. You may also want to read [Training/Test tips](tips.md) for more suggestions.
+
+#### Connection Error:HTTPConnectionPool ([#230](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/230), [#24](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/24), [#38](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/38))
+
+Similar error messages include “Failed to establish a new connection/Connection refused”.
+
+Please start the visdom server before starting the training:
+
+```bash
+python -m visdom.server
+```
+
+To install the visdom, you can use the following command:
+
+```bash
+pip install visdom
+```
+
+You can also disable the visdom by setting `--display_id 0`.
+
+#### My PyTorch errors on CUDA related code.
+
+Try to run the following code snippet to make sure that CUDA is working (assuming using PyTorch >= 0.4):
+
+```python
+import torch
+torch.cuda.init()
+print(torch.randn(1, device='cuda'))
+```
+
+If you met an error, it is likely that your PyTorch build does not work with CUDA, e.g., it is installed from the official MacOS binary, or you have a GPU that is too old and not supported anymore. You may run the the code with CPU using `--gpu_ids -1`.
+
+#### TypeError: Object of type 'Tensor' is not JSON serializable ([#258](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/258))
+
+Similar errors: AttributeError: module 'torch' has no attribute 'device' ([#314](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/314))
+
+The current code only works with PyTorch 2.4+. An earlier PyTorch version can often cause the above errors.
+
+#### ValueError: empty range for randrange() ([#390](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/390), [#376](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/376), [#194](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/194))
+
+Similar error messages include "ConnectionRefusedError: [Errno 111] Connection refused"
+
+It is related to the data augmentation step. It often happens when you use `--preprocess crop`. The program will crop random `crop_size x crop_size` patches out of the input training images. But if some of your image sizes (e.g., `256x384`) are smaller than the `crop_size` (e.g., 512), you will get this error. A simple fix will be to use other data augmentation methods such as `resize_and_crop` or `scale_width_and_crop`. Our program will automatically resize the images according to `load_size` before apply `crop_size x crop_size` cropping. Make sure that `load_size >= crop_size`.
+
+#### Can I continue/resume my training? ([#350](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/350), [#275](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/275), [#234](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/234), [#87](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/87))
+
+You can use the option `--continue_train`. Also set `--epoch_count` to specify a different starting epoch count. See more discussion in [training/test tips](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/blob/master/docs/tips.md#trainingtest-tips).
+
+#### Why does my training loss not converge? ([#335](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/335), [#164](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/164), [#30](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/30))
+
+Many GAN losses do not converge (exception: WGAN, WGAN-GP, etc. ) due to the nature of minimax optimization. For DCGAN and LSGAN objective, it is quite normal for the G and D losses to go up and down. It should be fine as long as they do not blow up.
+
+#### How can I make it work for my own data (e.g., 16-bit png, tiff, hyperspectral images)? ([#309](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/309), [#320](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/), [#202](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/202))
+
+The current code only supports RGB and grayscale images. If you would like to train the model on other data types, please follow the following steps:
+
+- change the parameters `--input_nc` and `--output_nc` to the number of channels in your input/output images.
+- Write your own custom data loader (It is easy as long as you know how to load your data with python). If you write a new data loader class, you need to change the flag `--dataset_mode` accordingly. Alternatively, you can modify the existing data loader. For aligned datasets, change this [line](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/blob/master/data/aligned_dataset.py#L41); For unaligned datasets, change these two [lines](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/blob/master/data/unaligned_dataset.py#L57).
+
+- If you use visdom and HTML to visualize the results, you may also need to change the visualization code.
+
+#### Multi-GPU Training ([#327](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/327), [#292](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/292), [#137](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/137), [#35](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/35))
+
+You can use Multi-GPU training by setting `--gpu_ids` (e.g., `--gpu_ids 0,1,2,3` for the first four GPUs on your machine.) To fully utilize all the GPUs, you need to increase your batch size. Try `--batch_size 4`, `--batch_size 16`, or even a larger batch_size. Each GPU will process batch_size/#GPUs images. The optimal batch size depends on the number of GPUs you have, GPU memory per GPU, and the resolution of your training images.
+
+We also recommend that you use the instance normalization for multi-GPU training by setting `--norm instance`. The current batch normalization might not work for multi-GPUs as the batchnorm parameters are not shared across different GPUs. Advanced users can try [synchronized batchnorm](https://github.com/vacancy/Synchronized-BatchNorm-PyTorch).
+
+#### Can I run the model on CPU? ([#310](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/310))
+
+Yes, you can set `--gpu_ids -1`. See [training/test tips](tips.md) for more details.
+
+#### Are pre-trained models available? ([#10](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/10))
+
+Yes, you can download pretrained models with the bash script `./scripts/download_cyclegan_model.sh`. See [here](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix#apply-a-pre-trained-model-cyclegan) for more details. We are slowly adding more models to the repo.
+
+#### Out of memory ([#174](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/174))
+
+CycleGAN is more memory-intensive than pix2pix as it requires two generators and two discriminators. If you would like to produce high-resolution images, you can do the following.
+
+- During training, train CycleGAN on cropped images of the training set. Please be careful not to change the aspect ratio or the scale of the original image, as this can lead to the training/test gap. You can usually do this by using `--preprocess crop` option, or `--preprocess scale_width_and_crop`.
+
+- Then at test time, you can load only one generator to produce the results in a single direction. This greatly saves GPU memory as you are not loading the discriminators and the other generator in the opposite direction. You can probably take the whole image as input. You can do this using `--model test --dataroot [path to the directory that contains your test images (e.g., ./datasets/horse2zebra/trainA)] --model_suffix _A --preprocess none`. You can use either `--preprocess none` or `--preprocess scale_width --crop_size [your_desired_image_width]`. Please see the [model_suffix](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/blob/master/models/test_model.py#L16) and [preprocess](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/blob/master/data/base_dataset.py#L24) for more details.
+
+#### RuntimeError: Error(s) in loading state_dict ([#812](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/812), [#671](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/671),[#461](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/461), [#296](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/296))
+
+If you get the above errors when loading the generator during test time, you probably have used different network configurations for training and test. There are a few things to check: (1) the network architecture `--netG`: you will get an error if you use `--netG unet256` during training, and use `--netG resnet_6blocks` during test. Make sure that the flag is the same. (2) the normalization parameters `--norm`: we use different default `--norm` parameters for `--model cycle_gan`, `--model pix2pix`, and `--model test`. They might be different from the one you used in your training time. Make sure that you add the `--norm` flag in your test code. (3) If you use dropout during training time, make sure that you use the same Dropout setting in your test. Check the flag `--no_dropout`.
+
+Note that we use different default generators, normalization, and dropout options for different models. The model file can overwrite the default arguments and add new arguments. For example, this [line](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/blob/master/models/pix2pix_model.py#L32) adds and changes default arguments for pix2pix. For CycleGAN, the default is `--netG resnet_9blocks --no_dropout --norm instance --dataset_mode unaligned`. For pix2pix, the default is `--netG unet_256 --norm batch --dataset_mode aligned`. For model testing with single direction (`--model test`), the default is `--netG resnet_9blocks --norm instance --dataset_mode single`. To make sure that your training and test follow the same setting, you are encouraged to plicitly specify the `--netG`, `--norm`, `--dataset_mode`, and `--no_dropout` (or not) in your script.
+
+#### NotSupportedError ([#829](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/829))
+
+The error message states that `slicing multiple dimensions at the same time isn't supported yet proposals (Tensor): boxes to be encoded`. It is not related to our repo. It is often caused by incompatibility between the `torhvision` version and `pytorch` version. You need to re-intall or upgrade your `torchvision` to be compatible with the `pytorch` version.
+
+#### What is the identity loss? ([#322](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/322), [#373](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/373), [#362](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/pull/362))
+
+We use the identity loss for our photo to painting application. The identity loss can regularize the generator to be close to an identity mapping when fed with real samples from the _target_ domain. If something already looks like from the target domain, you should preserve the image without making additional changes. The generator trained with this loss will often be more conservative for unknown content. Please see more details in Sec 5.2 ''Photo generation from paintings'' and Figure 12 in the CycleGAN [paper](https://arxiv.org/pdf/1703.10593.pdf). The loss was first proposed in Equation 6 of the prior work [[Taigman et al., 2017]](https://arxiv.org/pdf/1611.02200.pdf).
+
+#### The color gets inverted from the beginning of training ([#249](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/249))
+
+The authors also observe that the generator unnecessarily inverts the color of the input image early in training, and then never learns to undo the inversion. In this case, you can try two things.
+
+- First, try using identity loss `--lambda_identity 1.0` or `--lambda_identity 0.1`. We observe that the identity loss makes the generator to be more conservative and make fewer unnecessary changes. However, because of this, the change may not be as dramatic.
+
+- Second, try smaller variance when initializing weights by changing `--init_gain`. We observe that a smaller variance in weight initialization results in less color inversion.
+
+#### For labels2photo Cityscapes evaluation, why does the pretrained FCN-8s model not work well on the original Cityscapes input images? ([#150](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/150))
+
+The model was trained on 256x256 images that are resized/upsampled to 1024x2048, so expected input images to the network are very blurry. The purpose of the resizing was to 1) keep the label maps in the original high resolution untouched and 2) avoid the need to change the standard FCN training code for Cityscapes.
+
+#### How do I get the `ground-truth` numbers on the labels2photo Cityscapes evaluation? ([#150](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/150))
+
+You need to resize the original Cityscapes images to 256x256 before running the evaluation code.
+
+#### What is a good evaluation metric for CycleGAN? ([#730](https://github.com/pulls), [#716](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/716), [#166](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/166))
+
+The evaluation metric highly depends on your specific task and dataset. There is no single metric that works for all the datasets and tasks.
+
+There are a few popular choices: (1) we often evaluate CycleGAN on paired datasets (e.g., Cityscapes dataset and the meanIOU metric used in the CycleGAN paper), in which the model was trained without pairs. (2) Many researchers have adopted standard GAN metrics such as FID. Note that FID only evaluates the output images, while it ignores the correspondence between output and input. (3) A user study regarding photorealism might be helpful. Please check out the details of a user study in the CycleGAN paper (Section 5.1.1).
+
+In summary, how to automatically evaluate the results is an open research problem for GANs research. But for many creative applications, the results are subjective and hard to quantify without humans in the loop.
+
+#### What dose the CycleGAN loss look like if training goes well? ([#1096](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/1096), [#1086](ttps://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/1086), [#288](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/288), [#30](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/30))
+
+Typically, the cycle-consistency loss and identity loss decrease during training, while GAN losses oscillate. To evaluate the quality of your results, you need to adopt additional evaluation metrics to your training and test images. See the Q & A above.
+
+#### Using resize-conv to reduce checkerboard artifacts ([#190](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/190), [#64](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/64))
+
+This Distill [blog](https://distill.pub/2016/deconv-checkerboard/) discussed one of the potential causes of the checkerboard artifacts. You can fix that issue by switching from "deconvolution" to nearest-neighbor upsampling, followed by regular convolution. Here is one implementation provided by [@SsnL](https://github.com/SsnL). You can replace the ConvTranspose2d with the following layers.
+
+```python
+nn.Upsample(scale_factor = 2, mode='bilinear'),
+nn.ReflectionPad2d(1),
+nn.Conv2d(ngf * mult, int(ngf * mult / 2), kernel_size=3, stride=1, padding=0),
+```
+
+We have also noticed that sometimes the checkboard artifacts will go away if you train long enough. Maybe you can try training your model a bit longer.
+
+#### pix2pix/CycleGAN has no random noise z ([#152](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/152))
+
+The current pix2pix/CycleGAN model does not take z as input. In both pix2pix and CycleGAN, we tried to add z to the generator: e.g., adding z to a latent state, concatenating with a latent state, applying dropout, etc., but often found the output did not vary significantly as a function of z. Conditional GANs do not need noise as long as the input is sufficiently complex so that the input can kind of play the role of noise. Without noise, the mapping is deterministic.
+
+Please check out the following papers that show ways of getting z to actually have a substantial effect: e.g., [BicycleGAN](https://github.com/junyanz/BicycleGAN), [AugmentedCycleGAN](https://arxiv.org/abs/1802.10151), [MUNIT](https://arxiv.org/abs/1804.04732), [DRIT](https://arxiv.org/pdf/1808.00948.pdf), etc.
+
+#### Experiment details (e.g., BW->color) ([#306](https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/306))
+
+You can find more training details and hyperparameter settings in the appendix of [CycleGAN](https://arxiv.org/abs/1703.10593) and [pix2pix](https://arxiv.org/abs/1611.07004) papers.
+
+#### Results with [Cycada](https://arxiv.org/pdf/1711.03213.pdf)
+
+We generated the [result of translating GTA images to Cityscapes-style images](https://junyanz.github.io/CycleGAN/) using our Torch repo. Our PyTorch and Torch implementation seemed to produce a little bit different results, although we have not measured the FCN score using the PyTorch-trained model. To reproduce the result of Cycada, please use the Torch repo for now.
+
+#### Loading and using the saved model in your code
+
+You can easily consume the model in your code using the below code snippet:
+
+```python
+import torch
+from models.networks import define_G
+from collections import OrderedDict
+
+model_dict = torch.load("checkpoints/stars_pix2pix/latest_net_G.pth")
+new_dict = OrderedDict()
+for k, v in model_dict.items():
+ # load_state_dict expects keys with prefix 'module.'
+ new_dict["module." + k] = v
+
+# make sure you pass the correct parameters to the define_G method
+generator_model = define_G(input_nc=1,output_nc=1,ngf=64,netG="resnet_9blocks",
+ norm="batch",use_dropout=True,init_gain=0.02,gpu_ids=[0])
+generator_model.load_state_dict(new_dict)
+```
+
+If everything goes well you should see a '\' message.
diff --git a/pix2pix_vgg/docs/tips.md b/pix2pix_vgg/docs/tips.md
new file mode 100644
index 0000000000000000000000000000000000000000..bae60b1ef97079d64de135f753fb78c1f2fe6869
--- /dev/null
+++ b/pix2pix_vgg/docs/tips.md
@@ -0,0 +1,74 @@
+## Training/test Tips
+#### Training/test options
+Please see `options/train_options.py` and `options/base_options.py` for the training flags; see `options/test_options.py` and `options/base_options.py` for the test flags. There are some model-specific flags as well, which are added in the model files, such as `--lambda_A` option in `model/cycle_gan_model.py`. The default values of these options are also adjusted in the model files.
+#### CPU/GPU (default `--gpu_ids 0`)
+Please set`--gpu_ids -1` to use CPU mode; set `--gpu_ids 0,1,2` for multi-GPU mode. You need a large batch size (e.g., `--batch_size 32`) to benefit from multiple GPUs.
+
+#### Visualization
+During training, the current results can be viewed using two methods. First, the intermediate results are saved to `[opt.checkpoints_dir]/[opt.name]/web/` as an HTML file. To avoid this, set `--no_html`. Second, if you set `--use_wandb`, the results and loss plots will appear on your Weights & Biases dashboard.
+
+#### Preprocessing
+ Images can be resized and cropped in different ways using `--preprocess` option. The default option `'resize_and_crop'` resizes the image to be of size `(opt.load_size, opt.load_size)` and does a random crop of size `(opt.crop_size, opt.crop_size)`. `'crop'` skips the resizing step and only performs random cropping. `'scale_width'` resizes the image to have width `opt.crop_size` while keeping the aspect ratio. `'scale_width_and_crop'` first resizes the image to have width `opt.load_size` and then does random cropping of size `(opt.crop_size, opt.crop_size)`. `'none'` tries to skip all these preprocessing steps. However, if the image size is not a multiple of some number depending on the number of downsamplings of the generator, you will get an error because the size of the output image may be different from the size of the input image. Therefore, `'none'` option still tries to adjust the image size to be a multiple of 4. You might need a bigger adjustment if you change the generator architecture. Please see `data/base_dataset.py` do see how all these were implemented.
+
+#### Fine-tuning/resume training
+To fine-tune a pre-trained model, or resume the previous training, use the `--continue_train` flag. The program will then load the model based on `epoch`. By default, the program will initialize the epoch count as 1. Set `--epoch_count ` to specify a different starting epoch count.
+
+
+#### Prepare your own datasets for CycleGAN
+You need to create two directories to host images from domain A `/path/to/data/trainA` and from domain B `/path/to/data/trainB`. Then you can train the model with the dataset flag `--dataroot /path/to/data`. Optionally, you can create hold-out test datasets at `/path/to/data/testA` and `/path/to/data/testB` to test your model on unseen images.
+
+#### Prepare your own datasets for pix2pix
+Pix2pix's training requires paired data. We provide a python script to generate training data in the form of pairs of images {A,B}, where A and B are two different depictions of the same underlying scene. For example, these might be pairs {label map, photo} or {bw image, color image}. Then we can learn to translate A to B or B to A:
+
+Create folder `/path/to/data` with subdirectories `A` and `B`. `A` and `B` should each have their own subdirectories `train`, `val`, `test`, etc. In `/path/to/data/A/train`, put training images in style A. In `/path/to/data/B/train`, put the corresponding images in style B. Repeat same for other data splits (`val`, `test`, etc).
+
+Corresponding images in a pair {A,B} must be the same size and have the same filename, e.g., `/path/to/data/A/train/1.jpg` is considered to correspond to `/path/to/data/B/train/1.jpg`.
+
+Once the data is formatted this way, call:
+```bash
+python datasets/combine_A_and_B.py --fold_A /path/to/data/A --fold_B /path/to/data/B --fold_AB /path/to/data
+```
+
+This will combine each pair of images (A,B) into a single image file, ready for training.
+
+
+#### About image size
+ Since the generator architecture in CycleGAN involves a series of downsampling / upsampling operations, the size of the input and output image may not match if the input image size is not a multiple of 4. As a result, you may get a runtime error because the L1 identity loss cannot be enforced with images of different size. Therefore, we slightly resize the image to become multiples of 4 even with `--preprocess none` option. For the same reason, `--crop_size` needs to be a multiple of 4.
+
+#### Training/Testing with high res images
+CycleGAN is quite memory-intensive as four networks (two generators and two discriminators) need to be loaded on one GPU, so a large image cannot be entirely loaded. In this case, we recommend training with cropped images. For example, to generate 1024px results, you can train with `--preprocess scale_width_and_crop --load_size 1024 --crop_size 360`, and test with `--preprocess scale_width --load_size 1024`. This way makes sure the training and test will be at the same scale. At test time, you can afford higher resolution because you don’t need to load all networks.
+
+#### Training/Testing with rectangular images
+Both pix2pix and CycleGAN can work for rectangular images. To make them work, you need to use different preprocessing flags. Let's say that you are working with `360x256` images. During training, you can specify `--preprocess crop` and `--crop_size 256`. This will allow your model to be trained on randomly cropped `256x256` images during training time. During test time, you can apply the model on `360x256` images with the flag `--preprocess none`.
+
+There are practical restrictions regarding image sizes for each generator architecture. For `unet256`, it only supports images whose width and height are divisible by 256. For `unet128`, the width and height need to be divisible by 128. For `resnet_6blocks` and `resnet_9blocks`, the width and height need to be divisible by 4.
+
+#### About loss curve
+Unfortunately, the loss curve does not reveal much information in training GANs, and CycleGAN is no exception. To check whether the training has converged or not, we recommend periodically generating a few samples and looking at them.
+
+#### About batch size
+For all experiments in the paper, we set the batch size to be 1. If there is room for memory, you can use higher batch size with batch norm or instance norm. (Note that the default batchnorm does not work well with multi-GPU training. You may consider using [synchronized batchnorm](https://github.com/vacancy/Synchronized-BatchNorm-PyTorch) instead). But please be aware that it can impact the training. In particular, even with Instance Normalization, different batch sizes can lead to different results. Moreover, increasing `--crop_size` may be a good alternative to increasing the batch size.
+
+
+#### Notes on Colorization
+No need to run `combine_A_and_B.py` for colorization. Instead, you need to prepare natural images and set `--dataset_mode colorization` and `--model colorization` in the script. The program will automatically convert each RGB image into Lab color space, and create `L -> ab` image pair during the training. Also set `--input_nc 1` and `--output_nc 2`. The training and test directory should be organized as `/your/data/train` and `your/data/test`. See example scripts `scripts/train_colorization.sh` and `scripts/test_colorization` for more details.
+
+#### Notes on Extracting Edges
+We provide python and Matlab scripts to extract coarse edges from photos. Run `scripts/edges/batch_hed.py` to compute [HED](https://github.com/s9xie/hed) edges. Run `scripts/edges/PostprocessHED.m` to simplify edges with additional post-processing steps. Check the code documentation for more details.
+
+#### Evaluating Labels2Photos on Cityscapes
+We provide scripts for running the evaluation of the Labels2Photos task on the Cityscapes **validation** set. We assume that you have installed `caffe` (and `pycaffe`) in your system. If not, see the [official website](http://caffe.berkeleyvision.org/installation.html) for installation instructions. Once `caffe` is successfully installed, download the pre-trained FCN-8s semantic segmentation model (512MB) by running
+```bash
+bash ./scripts/eval_cityscapes/download_fcn8s.sh
+```
+Then make sure `./scripts/eval_cityscapes/` is in your system's python path. If not, run the following command to add it
+```bash
+export PYTHONPATH=${PYTHONPATH}:./scripts/eval_cityscapes/
+```
+Now you can run the following command to evaluate your predictions:
+```bash
+python ./scripts/eval_cityscapes/evaluate.py --cityscapes_dir /path/to/original/cityscapes/dataset/ --result_dir /path/to/your/predictions/ --output_dir /path/to/output/directory/
+```
+Images stored under `--result_dir` should contain your model predictions on the Cityscapes **validation** split, and have the original Cityscapes naming convention (e.g., `frankfurt_000001_038418_leftImg8bit.png`). The script will output a text file under `--output_dir` containing the metric.
+
+**Further notes**: Our pre-trained FCN model is **not** supposed to work on Cityscapes in the original resolution (1024x2048) as it was trained on 256x256 images that are then upsampled to 1024x2048 during training. The purpose of the resizing during training was to 1) keep the label maps in the original high resolution untouched and 2) avoid the need of changing the standard FCN training code and the architecture for Cityscapes. During test time, you need to synthesize 256x256 results. Our test code will automatically upsample your results to 1024x2048 before feeding them to the pre-trained FCN model. The output is at 1024x2048 resolution and will be compared to 1024x2048 ground truth labels. You do not need to resize the ground truth labels. The best way to verify whether everything is correct is to reproduce the numbers for real images in the paper first. To achieve it, you need to resize the original/real Cityscapes images (**not** labels) to 256x256 and feed them to the evaluation code.
diff --git a/pix2pix_vgg/environment.yml b/pix2pix_vgg/environment.yml
new file mode 100644
index 0000000000000000000000000000000000000000..96f60da27fe744556f7b925111bf5799d7fb919d
--- /dev/null
+++ b/pix2pix_vgg/environment.yml
@@ -0,0 +1,17 @@
+name: pytorch-img2img
+channels:
+ - pytorch
+ - conda-forge
+ - nvidia
+dependencies:
+ - python=3.11
+ - pytorch=2.4.0
+ - torchvision=0.19.0
+ - pytorch-cuda=12.1
+ - numpy=1.24.3
+ - scikit-image
+ - pip
+ - pip:
+ - dominate>=2.8.0
+ - Pillow>=10.0.0
+ - wandb>=0.16.0
diff --git a/pix2pix_vgg/eval_range.sh b/pix2pix_vgg/eval_range.sh
new file mode 100644
index 0000000000000000000000000000000000000000..94b03543afd6166a9e6d225de6d97e5beded6bcc
--- /dev/null
+++ b/pix2pix_vgg/eval_range.sh
@@ -0,0 +1,18 @@
+for ep in $(seq 100 5 200); do
+ echo "=== Evaluating epoch $ep ==="
+
+ CUDA_VISIBLE_DEVICES=0 python test.py \
+ --dataroot datasets/rhino_aligned \
+ --checkpoints_dir checkpoints \
+ --name rhino_pix2pix_roi \
+ --model pix2pix --direction AtoB \
+ --dataset_mode aligned --preprocess none \
+ --epoch $ep --num_test -1 \
+ --results_dir results/ep${ep}
+
+ python tools/evaluate.py \
+ --results_root results \
+ --epoch ${ep} \
+ --mask_dir datasets/rhino_aligned/val_masks \
+ --out_csv metrics_val.csv
+done
diff --git a/pix2pix_vgg/imgs/edges2cats.jpg b/pix2pix_vgg/imgs/edges2cats.jpg
new file mode 100644
index 0000000000000000000000000000000000000000..be5c1412eb0decea00d7f62e609bab555fa6b0e2
Binary files /dev/null and b/pix2pix_vgg/imgs/edges2cats.jpg differ
diff --git a/pix2pix_vgg/imgs/horse2zebra.gif b/pix2pix_vgg/imgs/horse2zebra.gif
new file mode 100644
index 0000000000000000000000000000000000000000..4ded4d1ec2f5438765418c8a32d5e6f401b7d5cf
--- /dev/null
+++ b/pix2pix_vgg/imgs/horse2zebra.gif
@@ -0,0 +1,3 @@
+version https://git-lfs.github.com/spec/v1
+oid sha256:16a76adedd309c46ba6ed63f89b14130c4a671fd6febc26fb0372a1ccf16c7aa
+size 7686299
diff --git a/pix2pix_vgg/logs/eval_2025-09-17_160552_gpu2.log b/pix2pix_vgg/logs/eval_2025-09-17_160552_gpu2.log
new file mode 100644
index 0000000000000000000000000000000000000000..c2c35e640e3af61676454f2447d82f1bb57cdfb4
--- /dev/null
+++ b/pix2pix_vgg/logs/eval_2025-09-17_160552_gpu2.log
@@ -0,0 +1,641 @@
+[2025年 09月 17日 星期三 16:05:53 CST] 评估观察者启动(GPU2)
+[2025年 09月 17日 星期三 18:02:53 CST] 评估 epoch 5
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/test.py", line 32, in
+ from options.test_options import TestOptions
+ File "/data1/liutao/pix2pix/options/test_options.py", line 1, in
+ from .base_options import BaseOptions
+ File "/data1/liutao/pix2pix/options/base_options.py", line 3, in
+ from util import util
+ File "/data1/liutao/pix2pix/util/util.py", line 4, in
+ import torch
+ModuleNotFoundError: No module named 'torch'
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/tools/evaluate.py", line 4, in
+ import numpy as np
+ModuleNotFoundError: No module named 'numpy'
+[2025年 09月 17日 星期三 18:02:53 CST] 完成评估 epoch 5
+[2025年 09月 17日 星期三 18:09:53 CST] 评估 epoch 10
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/test.py", line 32, in
+ from options.test_options import TestOptions
+ File "/data1/liutao/pix2pix/options/test_options.py", line 1, in
+ from .base_options import BaseOptions
+ File "/data1/liutao/pix2pix/options/base_options.py", line 3, in
+ from util import util
+ File "/data1/liutao/pix2pix/util/util.py", line 4, in
+ import torch
+ModuleNotFoundError: No module named 'torch'
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/tools/evaluate.py", line 4, in
+ import numpy as np
+ModuleNotFoundError: No module named 'numpy'
+[2025年 09月 17日 星期三 18:09:53 CST] 完成评估 epoch 10
+[2025年 09月 17日 星期三 18:17:53 CST] 评估 epoch 15
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/test.py", line 32, in
+ from options.test_options import TestOptions
+ File "/data1/liutao/pix2pix/options/test_options.py", line 1, in
+ from .base_options import BaseOptions
+ File "/data1/liutao/pix2pix/options/base_options.py", line 3, in
+ from util import util
+ File "/data1/liutao/pix2pix/util/util.py", line 4, in
+ import torch
+ModuleNotFoundError: No module named 'torch'
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/tools/evaluate.py", line 4, in
+ import numpy as np
+ModuleNotFoundError: No module named 'numpy'
+[2025年 09月 17日 星期三 18:17:53 CST] 完成评估 epoch 15
+[2025年 09月 17日 星期三 18:24:53 CST] 评估 epoch 20
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/test.py", line 32, in
+ from options.test_options import TestOptions
+ File "/data1/liutao/pix2pix/options/test_options.py", line 1, in
+ from .base_options import BaseOptions
+ File "/data1/liutao/pix2pix/options/base_options.py", line 3, in
+ from util import util
+ File "/data1/liutao/pix2pix/util/util.py", line 4, in
+ import torch
+ModuleNotFoundError: No module named 'torch'
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/tools/evaluate.py", line 4, in
+ import numpy as np
+ModuleNotFoundError: No module named 'numpy'
+[2025年 09月 17日 星期三 18:24:53 CST] 完成评估 epoch 20
+[2025年 09月 17日 星期三 18:31:53 CST] 评估 epoch 25
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/test.py", line 32, in
+ from options.test_options import TestOptions
+ File "/data1/liutao/pix2pix/options/test_options.py", line 1, in
+ from .base_options import BaseOptions
+ File "/data1/liutao/pix2pix/options/base_options.py", line 3, in
+ from util import util
+ File "/data1/liutao/pix2pix/util/util.py", line 4, in
+ import torch
+ModuleNotFoundError: No module named 'torch'
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/tools/evaluate.py", line 4, in
+ import numpy as np
+ModuleNotFoundError: No module named 'numpy'
+[2025年 09月 17日 星期三 18:31:53 CST] 完成评估 epoch 25
+[2025年 09月 17日 星期三 18:39:53 CST] 评估 epoch 30
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/test.py", line 32, in
+ from options.test_options import TestOptions
+ File "/data1/liutao/pix2pix/options/test_options.py", line 1, in
+ from .base_options import BaseOptions
+ File "/data1/liutao/pix2pix/options/base_options.py", line 3, in
+ from util import util
+ File "/data1/liutao/pix2pix/util/util.py", line 4, in
+ import torch
+ModuleNotFoundError: No module named 'torch'
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/tools/evaluate.py", line 4, in
+ import numpy as np
+ModuleNotFoundError: No module named 'numpy'
+[2025年 09月 17日 星期三 18:39:54 CST] 完成评估 epoch 30
+[2025年 09月 17日 星期三 18:46:54 CST] 评估 epoch 35
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/test.py", line 32, in
+ from options.test_options import TestOptions
+ File "/data1/liutao/pix2pix/options/test_options.py", line 1, in
+ from .base_options import BaseOptions
+ File "/data1/liutao/pix2pix/options/base_options.py", line 3, in
+ from util import util
+ File "/data1/liutao/pix2pix/util/util.py", line 4, in
+ import torch
+ModuleNotFoundError: No module named 'torch'
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/tools/evaluate.py", line 4, in
+ import numpy as np
+ModuleNotFoundError: No module named 'numpy'
+[2025年 09月 17日 星期三 18:46:54 CST] 完成评估 epoch 35
+[2025年 09月 17日 星期三 18:53:54 CST] 评估 epoch 40
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/test.py", line 32, in
+ from options.test_options import TestOptions
+ File "/data1/liutao/pix2pix/options/test_options.py", line 1, in
+ from .base_options import BaseOptions
+ File "/data1/liutao/pix2pix/options/base_options.py", line 3, in
+ from util import util
+ File "/data1/liutao/pix2pix/util/util.py", line 4, in
+ import torch
+ModuleNotFoundError: No module named 'torch'
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/tools/evaluate.py", line 4, in
+ import numpy as np
+ModuleNotFoundError: No module named 'numpy'
+[2025年 09月 17日 星期三 18:53:54 CST] 完成评估 epoch 40
+[2025年 09月 17日 星期三 19:01:54 CST] 评估 epoch 45
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/test.py", line 32, in
+ from options.test_options import TestOptions
+ File "/data1/liutao/pix2pix/options/test_options.py", line 1, in
+ from .base_options import BaseOptions
+ File "/data1/liutao/pix2pix/options/base_options.py", line 3, in
+ from util import util
+ File "/data1/liutao/pix2pix/util/util.py", line 4, in
+ import torch
+ModuleNotFoundError: No module named 'torch'
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/tools/evaluate.py", line 4, in
+ import numpy as np
+ModuleNotFoundError: No module named 'numpy'
+[2025年 09月 17日 星期三 19:01:54 CST] 完成评估 epoch 45
+[2025年 09月 17日 星期三 19:08:54 CST] 评估 epoch 50
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/test.py", line 32, in
+ from options.test_options import TestOptions
+ File "/data1/liutao/pix2pix/options/test_options.py", line 1, in
+ from .base_options import BaseOptions
+ File "/data1/liutao/pix2pix/options/base_options.py", line 3, in
+ from util import util
+ File "/data1/liutao/pix2pix/util/util.py", line 4, in
+ import torch
+ModuleNotFoundError: No module named 'torch'
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/tools/evaluate.py", line 4, in
+ import numpy as np
+ModuleNotFoundError: No module named 'numpy'
+[2025年 09月 17日 星期三 19:08:54 CST] 完成评估 epoch 50
+[2025年 09月 17日 星期三 19:15:54 CST] 评估 epoch 55
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/test.py", line 32, in
+ from options.test_options import TestOptions
+ File "/data1/liutao/pix2pix/options/test_options.py", line 1, in
+ from .base_options import BaseOptions
+ File "/data1/liutao/pix2pix/options/base_options.py", line 3, in
+ from util import util
+ File "/data1/liutao/pix2pix/util/util.py", line 4, in
+ import torch
+ModuleNotFoundError: No module named 'torch'
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/tools/evaluate.py", line 4, in
+ import numpy as np
+ModuleNotFoundError: No module named 'numpy'
+[2025年 09月 17日 星期三 19:15:54 CST] 完成评估 epoch 55
+[2025年 09月 17日 星期三 19:23:54 CST] 评估 epoch 60
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/test.py", line 32, in
+ from options.test_options import TestOptions
+ File "/data1/liutao/pix2pix/options/test_options.py", line 1, in
+ from .base_options import BaseOptions
+ File "/data1/liutao/pix2pix/options/base_options.py", line 3, in
+ from util import util
+ File "/data1/liutao/pix2pix/util/util.py", line 4, in
+ import torch
+ModuleNotFoundError: No module named 'torch'
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/tools/evaluate.py", line 4, in
+ import numpy as np
+ModuleNotFoundError: No module named 'numpy'
+[2025年 09月 17日 星期三 19:23:54 CST] 完成评估 epoch 60
+[2025年 09月 17日 星期三 19:30:54 CST] 评估 epoch 65
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/test.py", line 32, in
+ from options.test_options import TestOptions
+ File "/data1/liutao/pix2pix/options/test_options.py", line 1, in
+ from .base_options import BaseOptions
+ File "/data1/liutao/pix2pix/options/base_options.py", line 3, in
+ from util import util
+ File "/data1/liutao/pix2pix/util/util.py", line 4, in
+ import torch
+ModuleNotFoundError: No module named 'torch'
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/tools/evaluate.py", line 4, in
+ import numpy as np
+ModuleNotFoundError: No module named 'numpy'
+[2025年 09月 17日 星期三 19:30:54 CST] 完成评估 epoch 65
+[2025年 09月 17日 星期三 19:37:54 CST] 评估 epoch 70
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/test.py", line 32, in
+ from options.test_options import TestOptions
+ File "/data1/liutao/pix2pix/options/test_options.py", line 1, in
+ from .base_options import BaseOptions
+ File "/data1/liutao/pix2pix/options/base_options.py", line 3, in
+ from util import util
+ File "/data1/liutao/pix2pix/util/util.py", line 4, in
+ import torch
+ModuleNotFoundError: No module named 'torch'
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/tools/evaluate.py", line 4, in
+ import numpy as np
+ModuleNotFoundError: No module named 'numpy'
+[2025年 09月 17日 星期三 19:37:54 CST] 完成评估 epoch 70
+[2025年 09月 17日 星期三 19:45:54 CST] 评估 epoch 75
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/test.py", line 32, in
+ from options.test_options import TestOptions
+ File "/data1/liutao/pix2pix/options/test_options.py", line 1, in
+ from .base_options import BaseOptions
+ File "/data1/liutao/pix2pix/options/base_options.py", line 3, in
+ from util import util
+ File "/data1/liutao/pix2pix/util/util.py", line 4, in
+ import torch
+ModuleNotFoundError: No module named 'torch'
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/tools/evaluate.py", line 4, in
+ import numpy as np
+ModuleNotFoundError: No module named 'numpy'
+[2025年 09月 17日 星期三 19:45:54 CST] 完成评估 epoch 75
+[2025年 09月 17日 星期三 19:52:55 CST] 评估 epoch 80
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/test.py", line 32, in
+ from options.test_options import TestOptions
+ File "/data1/liutao/pix2pix/options/test_options.py", line 1, in
+ from .base_options import BaseOptions
+ File "/data1/liutao/pix2pix/options/base_options.py", line 3, in
+ from util import util
+ File "/data1/liutao/pix2pix/util/util.py", line 4, in
+ import torch
+ModuleNotFoundError: No module named 'torch'
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/tools/evaluate.py", line 4, in
+ import numpy as np
+ModuleNotFoundError: No module named 'numpy'
+[2025年 09月 17日 星期三 19:52:55 CST] 完成评估 epoch 80
+[2025年 09月 17日 星期三 19:59:55 CST] 评估 epoch 85
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/test.py", line 32, in
+ from options.test_options import TestOptions
+ File "/data1/liutao/pix2pix/options/test_options.py", line 1, in
+ from .base_options import BaseOptions
+ File "/data1/liutao/pix2pix/options/base_options.py", line 3, in
+ from util import util
+ File "/data1/liutao/pix2pix/util/util.py", line 4, in
+ import torch
+ModuleNotFoundError: No module named 'torch'
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/tools/evaluate.py", line 4, in
+ import numpy as np
+ModuleNotFoundError: No module named 'numpy'
+[2025年 09月 17日 星期三 19:59:55 CST] 完成评估 epoch 85
+[2025年 09月 17日 星期三 20:07:55 CST] 评估 epoch 90
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/test.py", line 32, in
+ from options.test_options import TestOptions
+ File "/data1/liutao/pix2pix/options/test_options.py", line 1, in
+ from .base_options import BaseOptions
+ File "/data1/liutao/pix2pix/options/base_options.py", line 3, in
+ from util import util
+ File "/data1/liutao/pix2pix/util/util.py", line 4, in
+ import torch
+ModuleNotFoundError: No module named 'torch'
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/tools/evaluate.py", line 4, in
+ import numpy as np
+ModuleNotFoundError: No module named 'numpy'
+[2025年 09月 17日 星期三 20:07:55 CST] 完成评估 epoch 90
+[2025年 09月 17日 星期三 20:14:55 CST] 评估 epoch 95
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/test.py", line 32, in
+ from options.test_options import TestOptions
+ File "/data1/liutao/pix2pix/options/test_options.py", line 1, in
+ from .base_options import BaseOptions
+ File "/data1/liutao/pix2pix/options/base_options.py", line 3, in
+ from util import util
+ File "/data1/liutao/pix2pix/util/util.py", line 4, in
+ import torch
+ModuleNotFoundError: No module named 'torch'
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/tools/evaluate.py", line 4, in
+ import numpy as np
+ModuleNotFoundError: No module named 'numpy'
+[2025年 09月 17日 星期三 20:14:55 CST] 完成评估 epoch 95
+[2025年 09月 17日 星期三 20:22:55 CST] 评估 epoch 100
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/test.py", line 32, in
+ from options.test_options import TestOptions
+ File "/data1/liutao/pix2pix/options/test_options.py", line 1, in
+ from .base_options import BaseOptions
+ File "/data1/liutao/pix2pix/options/base_options.py", line 3, in
+ from util import util
+ File "/data1/liutao/pix2pix/util/util.py", line 4, in
+ import torch
+ModuleNotFoundError: No module named 'torch'
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/tools/evaluate.py", line 4, in
+ import numpy as np
+ModuleNotFoundError: No module named 'numpy'
+[2025年 09月 17日 星期三 20:22:55 CST] 完成评估 epoch 100
+[2025年 09月 17日 星期三 20:29:55 CST] 评估 epoch 105
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/test.py", line 32, in
+ from options.test_options import TestOptions
+ File "/data1/liutao/pix2pix/options/test_options.py", line 1, in
+ from .base_options import BaseOptions
+ File "/data1/liutao/pix2pix/options/base_options.py", line 3, in
+ from util import util
+ File "/data1/liutao/pix2pix/util/util.py", line 4, in
+ import torch
+ModuleNotFoundError: No module named 'torch'
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/tools/evaluate.py", line 4, in
+ import numpy as np
+ModuleNotFoundError: No module named 'numpy'
+[2025年 09月 17日 星期三 20:29:55 CST] 完成评估 epoch 105
+[2025年 09月 17日 星期三 20:36:55 CST] 评估 epoch 110
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/test.py", line 32, in
+ from options.test_options import TestOptions
+ File "/data1/liutao/pix2pix/options/test_options.py", line 1, in
+ from .base_options import BaseOptions
+ File "/data1/liutao/pix2pix/options/base_options.py", line 3, in
+ from util import util
+ File "/data1/liutao/pix2pix/util/util.py", line 4, in
+ import torch
+ModuleNotFoundError: No module named 'torch'
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/tools/evaluate.py", line 4, in
+ import numpy as np
+ModuleNotFoundError: No module named 'numpy'
+[2025年 09月 17日 星期三 20:36:55 CST] 完成评估 epoch 110
+[2025年 09月 17日 星期三 20:44:55 CST] 评估 epoch 115
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/test.py", line 32, in
+ from options.test_options import TestOptions
+ File "/data1/liutao/pix2pix/options/test_options.py", line 1, in
+ from .base_options import BaseOptions
+ File "/data1/liutao/pix2pix/options/base_options.py", line 3, in
+ from util import util
+ File "/data1/liutao/pix2pix/util/util.py", line 4, in
+ import torch
+ModuleNotFoundError: No module named 'torch'
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/tools/evaluate.py", line 4, in
+ import numpy as np
+ModuleNotFoundError: No module named 'numpy'
+[2025年 09月 17日 星期三 20:44:55 CST] 完成评估 epoch 115
+[2025年 09月 17日 星期三 20:51:55 CST] 评估 epoch 120
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/test.py", line 32, in
+ from options.test_options import TestOptions
+ File "/data1/liutao/pix2pix/options/test_options.py", line 1, in
+ from .base_options import BaseOptions
+ File "/data1/liutao/pix2pix/options/base_options.py", line 3, in
+ from util import util
+ File "/data1/liutao/pix2pix/util/util.py", line 4, in
+ import torch
+ModuleNotFoundError: No module named 'torch'
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/tools/evaluate.py", line 4, in
+ import numpy as np
+ModuleNotFoundError: No module named 'numpy'
+[2025年 09月 17日 星期三 20:51:56 CST] 完成评估 epoch 120
+[2025年 09月 17日 星期三 20:58:56 CST] 评估 epoch 125
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/test.py", line 32, in
+ from options.test_options import TestOptions
+ File "/data1/liutao/pix2pix/options/test_options.py", line 1, in
+ from .base_options import BaseOptions
+ File "/data1/liutao/pix2pix/options/base_options.py", line 3, in
+ from util import util
+ File "/data1/liutao/pix2pix/util/util.py", line 4, in
+ import torch
+ModuleNotFoundError: No module named 'torch'
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/tools/evaluate.py", line 4, in
+ import numpy as np
+ModuleNotFoundError: No module named 'numpy'
+[2025年 09月 17日 星期三 20:58:56 CST] 完成评估 epoch 125
+[2025年 09月 17日 星期三 21:06:56 CST] 评估 epoch 130
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/test.py", line 32, in
+ from options.test_options import TestOptions
+ File "/data1/liutao/pix2pix/options/test_options.py", line 1, in
+ from .base_options import BaseOptions
+ File "/data1/liutao/pix2pix/options/base_options.py", line 3, in
+ from util import util
+ File "/data1/liutao/pix2pix/util/util.py", line 4, in
+ import torch
+ModuleNotFoundError: No module named 'torch'
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/tools/evaluate.py", line 4, in
+ import numpy as np
+ModuleNotFoundError: No module named 'numpy'
+[2025年 09月 17日 星期三 21:06:56 CST] 完成评估 epoch 130
+[2025年 09月 17日 星期三 21:13:56 CST] 评估 epoch 135
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/test.py", line 32, in
+ from options.test_options import TestOptions
+ File "/data1/liutao/pix2pix/options/test_options.py", line 1, in
+ from .base_options import BaseOptions
+ File "/data1/liutao/pix2pix/options/base_options.py", line 3, in
+ from util import util
+ File "/data1/liutao/pix2pix/util/util.py", line 4, in
+ import torch
+ModuleNotFoundError: No module named 'torch'
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/tools/evaluate.py", line 4, in
+ import numpy as np
+ModuleNotFoundError: No module named 'numpy'
+[2025年 09月 17日 星期三 21:13:56 CST] 完成评估 epoch 135
+[2025年 09月 17日 星期三 21:20:56 CST] 评估 epoch 140
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/test.py", line 32, in
+ from options.test_options import TestOptions
+ File "/data1/liutao/pix2pix/options/test_options.py", line 1, in
+ from .base_options import BaseOptions
+ File "/data1/liutao/pix2pix/options/base_options.py", line 3, in
+ from util import util
+ File "/data1/liutao/pix2pix/util/util.py", line 4, in
+ import torch
+ModuleNotFoundError: No module named 'torch'
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/tools/evaluate.py", line 4, in
+ import numpy as np
+ModuleNotFoundError: No module named 'numpy'
+[2025年 09月 17日 星期三 21:20:56 CST] 完成评估 epoch 140
+[2025年 09月 17日 星期三 21:28:56 CST] 评估 epoch 145
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/test.py", line 32, in
+ from options.test_options import TestOptions
+ File "/data1/liutao/pix2pix/options/test_options.py", line 1, in
+ from .base_options import BaseOptions
+ File "/data1/liutao/pix2pix/options/base_options.py", line 3, in
+ from util import util
+ File "/data1/liutao/pix2pix/util/util.py", line 4, in
+ import torch
+ModuleNotFoundError: No module named 'torch'
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/tools/evaluate.py", line 4, in
+ import numpy as np
+ModuleNotFoundError: No module named 'numpy'
+[2025年 09月 17日 星期三 21:28:56 CST] 完成评估 epoch 145
+[2025年 09月 17日 星期三 21:38:56 CST] 评估 epoch 150
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/test.py", line 32, in
+ from options.test_options import TestOptions
+ File "/data1/liutao/pix2pix/options/test_options.py", line 1, in
+ from .base_options import BaseOptions
+ File "/data1/liutao/pix2pix/options/base_options.py", line 3, in
+ from util import util
+ File "/data1/liutao/pix2pix/util/util.py", line 4, in
+ import torch
+ModuleNotFoundError: No module named 'torch'
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/tools/evaluate.py", line 4, in
+ import numpy as np
+ModuleNotFoundError: No module named 'numpy'
+[2025年 09月 17日 星期三 21:38:56 CST] 完成评估 epoch 150
+[2025年 09月 17日 星期三 21:46:56 CST] 评估 epoch 155
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/test.py", line 32, in
+ from options.test_options import TestOptions
+ File "/data1/liutao/pix2pix/options/test_options.py", line 1, in
+ from .base_options import BaseOptions
+ File "/data1/liutao/pix2pix/options/base_options.py", line 3, in
+ from util import util
+ File "/data1/liutao/pix2pix/util/util.py", line 4, in
+ import torch
+ModuleNotFoundError: No module named 'torch'
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/tools/evaluate.py", line 4, in
+ import numpy as np
+ModuleNotFoundError: No module named 'numpy'
+[2025年 09月 17日 星期三 21:46:56 CST] 完成评估 epoch 155
+[2025年 09月 17日 星期三 21:53:56 CST] 评估 epoch 160
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/test.py", line 32, in
+ from options.test_options import TestOptions
+ File "/data1/liutao/pix2pix/options/test_options.py", line 1, in
+ from .base_options import BaseOptions
+ File "/data1/liutao/pix2pix/options/base_options.py", line 3, in
+ from util import util
+ File "/data1/liutao/pix2pix/util/util.py", line 4, in
+ import torch
+ModuleNotFoundError: No module named 'torch'
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/tools/evaluate.py", line 4, in
+ import numpy as np
+ModuleNotFoundError: No module named 'numpy'
+[2025年 09月 17日 星期三 21:53:56 CST] 完成评估 epoch 160
+[2025年 09月 17日 星期三 22:01:56 CST] 评估 epoch 165
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/test.py", line 32, in
+ from options.test_options import TestOptions
+ File "/data1/liutao/pix2pix/options/test_options.py", line 1, in
+ from .base_options import BaseOptions
+ File "/data1/liutao/pix2pix/options/base_options.py", line 3, in
+ from util import util
+ File "/data1/liutao/pix2pix/util/util.py", line 4, in
+ import torch
+ModuleNotFoundError: No module named 'torch'
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/tools/evaluate.py", line 4, in
+ import numpy as np
+ModuleNotFoundError: No module named 'numpy'
+[2025年 09月 17日 星期三 22:01:57 CST] 完成评估 epoch 165
+[2025年 09月 17日 星期三 22:08:57 CST] 评估 epoch 170
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/test.py", line 32, in
+ from options.test_options import TestOptions
+ File "/data1/liutao/pix2pix/options/test_options.py", line 1, in
+ from .base_options import BaseOptions
+ File "/data1/liutao/pix2pix/options/base_options.py", line 3, in
+ from util import util
+ File "/data1/liutao/pix2pix/util/util.py", line 4, in
+ import torch
+ModuleNotFoundError: No module named 'torch'
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/tools/evaluate.py", line 4, in
+ import numpy as np
+ModuleNotFoundError: No module named 'numpy'
+[2025年 09月 17日 星期三 22:08:57 CST] 完成评估 epoch 170
+[2025年 09月 17日 星期三 22:17:57 CST] 评估 epoch 175
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/test.py", line 32, in
+ from options.test_options import TestOptions
+ File "/data1/liutao/pix2pix/options/test_options.py", line 1, in
+ from .base_options import BaseOptions
+ File "/data1/liutao/pix2pix/options/base_options.py", line 3, in
+ from util import util
+ File "/data1/liutao/pix2pix/util/util.py", line 4, in
+ import torch
+ModuleNotFoundError: No module named 'torch'
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/tools/evaluate.py", line 4, in
+ import numpy as np
+ModuleNotFoundError: No module named 'numpy'
+[2025年 09月 17日 星期三 22:17:57 CST] 完成评估 epoch 175
+[2025年 09月 17日 星期三 22:29:57 CST] 评估 epoch 180
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/test.py", line 32, in
+ from options.test_options import TestOptions
+ File "/data1/liutao/pix2pix/options/test_options.py", line 1, in
+ from .base_options import BaseOptions
+ File "/data1/liutao/pix2pix/options/base_options.py", line 3, in
+ from util import util
+ File "/data1/liutao/pix2pix/util/util.py", line 4, in
+ import torch
+ModuleNotFoundError: No module named 'torch'
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/tools/evaluate.py", line 4, in
+ import numpy as np
+ModuleNotFoundError: No module named 'numpy'
+[2025年 09月 17日 星期三 22:29:57 CST] 完成评估 epoch 180
+[2025年 09月 17日 星期三 22:40:57 CST] 评估 epoch 185
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/test.py", line 32, in
+ from options.test_options import TestOptions
+ File "/data1/liutao/pix2pix/options/test_options.py", line 1, in
+ from .base_options import BaseOptions
+ File "/data1/liutao/pix2pix/options/base_options.py", line 3, in
+ from util import util
+ File "/data1/liutao/pix2pix/util/util.py", line 4, in
+ import torch
+ModuleNotFoundError: No module named 'torch'
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/tools/evaluate.py", line 4, in
+ import numpy as np
+ModuleNotFoundError: No module named 'numpy'
+[2025年 09月 17日 星期三 22:40:57 CST] 完成评估 epoch 185
+[2025年 09月 17日 星期三 22:48:57 CST] 评估 epoch 190
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/test.py", line 32, in
+ from options.test_options import TestOptions
+ File "/data1/liutao/pix2pix/options/test_options.py", line 1, in
+ from .base_options import BaseOptions
+ File "/data1/liutao/pix2pix/options/base_options.py", line 3, in
+ from util import util
+ File "/data1/liutao/pix2pix/util/util.py", line 4, in
+ import torch
+ModuleNotFoundError: No module named 'torch'
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/tools/evaluate.py", line 4, in
+ import numpy as np
+ModuleNotFoundError: No module named 'numpy'
+[2025年 09月 17日 星期三 22:48:57 CST] 完成评估 epoch 190
+[2025年 09月 17日 星期三 22:55:57 CST] 评估 epoch 195
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/test.py", line 32, in
+ from options.test_options import TestOptions
+ File "/data1/liutao/pix2pix/options/test_options.py", line 1, in
+ from .base_options import BaseOptions
+ File "/data1/liutao/pix2pix/options/base_options.py", line 3, in
+ from util import util
+ File "/data1/liutao/pix2pix/util/util.py", line 4, in
+ import torch
+ModuleNotFoundError: No module named 'torch'
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/tools/evaluate.py", line 4, in
+ import numpy as np
+ModuleNotFoundError: No module named 'numpy'
+[2025年 09月 17日 星期三 22:55:57 CST] 完成评估 epoch 195
+[2025年 09月 17日 星期三 23:03:57 CST] 评估 epoch 200
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/test.py", line 32, in
+ from options.test_options import TestOptions
+ File "/data1/liutao/pix2pix/options/test_options.py", line 1, in
+ from .base_options import BaseOptions
+ File "/data1/liutao/pix2pix/options/base_options.py", line 3, in
+ from util import util
+ File "/data1/liutao/pix2pix/util/util.py", line 4, in
+ import torch
+ModuleNotFoundError: No module named 'torch'
+Traceback (most recent call last):
+ File "/data1/liutao/pix2pix/tools/evaluate.py", line 4, in
+ import numpy as np
+ModuleNotFoundError: No module named 'numpy'
+[2025年 09月 17日 星期三 23:03:57 CST] 完成评估 epoch 200
diff --git a/pix2pix_vgg/logs/eval_2025-09-17_165117_gpu2.log b/pix2pix_vgg/logs/eval_2025-09-17_165117_gpu2.log
new file mode 100644
index 0000000000000000000000000000000000000000..64df93300bb603d31a022ae288ed1be8b417f2f7
--- /dev/null
+++ b/pix2pix_vgg/logs/eval_2025-09-17_165117_gpu2.log
@@ -0,0 +1,2401 @@
+[2025年 09月 17日 星期三 16:51:18 CST] 评估观察者启动(GPU2)
+[2025年 09月 17日 星期三 18:02:18 CST] 评估 epoch 5
+----------------- Options ---------------
+ aspect_ratio: 1.0
+ batch_size: 1
+ checkpoints_dir: checkpoints [default: ./checkpoints]
+ crop_size: 256
+ dataroot: datasets/rhino_aligned [default: None]
+ dataset_mode: aligned
+ direction: AtoB
+ display_winsize: 256
+ epoch: 5 [default: latest]
+ eval: False
+ init_gain: 0.02
+ init_type: normal
+ input_nc: 3
+ isTrain: False [default: None]
+ lambda_roi: 0.0
+ load_iter: 0 [default: 0]
+ load_size: 256
+ masks_dir:
+ max_dataset_size: inf
+ model: pix2pix [default: test]
+ n_layers_D: 3
+ name: rhino_pix2pix_roi [default: experiment_name]
+ ndf: 64
+ netD: basic
+ netG: unet_256
+ ngf: 64
+ no_dropout: False
+ no_flip: False
+ norm: batch
+ num_test: -1 [default: 50]
+ num_threads: 4
+ output_nc: 3
+ phase: test
+ preprocess: none [default: resize_and_crop]
+ results_dir: results/ep5 [default: ./results/]
+ serial_batches: False
+ suffix:
+ use_wandb: False
+ verbose: False
+ wandb_project_name: CycleGAN-and-pix2pix
+----------------- End -------------------
+Traceback (most recent call last):
+ File "test.py", line 54, in
+ dataset = create_dataset(opt) # create a dataset given opt.dataset_mode and other options
+ File "/data1/liutao/pix2pix/data/__init__.py", line 60, in create_dataset
+ data_loader = CustomDatasetDataLoader(opt)
+ File "/data1/liutao/pix2pix/data/__init__.py", line 76, in __init__
+ self.dataset = dataset_class(opt)
+ File "/data1/liutao/pix2pix/data/aligned_dataset.py", line 16, in __init__
+ self.AB_paths = sorted(make_dataset(self.dir_AB, opt.max_dataset_size))
+ File "/data1/liutao/pix2pix/data/image_folder.py", line 36, in make_dataset
+ assert dir_path.is_dir(), f"{dir} is not a valid directory"
+AssertionError: datasets/rhino_aligned/test is not a valid directory
+Traceback (most recent call last):
+ File "tools/evaluate.py", line 7, in
+ import torch, lpips
+ModuleNotFoundError: No module named 'lpips'
+[2025年 09月 17日 星期三 18:02:22 CST] 完成评估 epoch 5
+[2025年 09月 17日 星期三 18:10:23 CST] 评估 epoch 10
+----------------- Options ---------------
+ aspect_ratio: 1.0
+ batch_size: 1
+ checkpoints_dir: checkpoints [default: ./checkpoints]
+ crop_size: 256
+ dataroot: datasets/rhino_aligned [default: None]
+ dataset_mode: aligned
+ direction: AtoB
+ display_winsize: 256
+ epoch: 10 [default: latest]
+ eval: False
+ init_gain: 0.02
+ init_type: normal
+ input_nc: 3
+ isTrain: False [default: None]
+ lambda_roi: 0.0
+ load_iter: 0 [default: 0]
+ load_size: 256
+ masks_dir:
+ max_dataset_size: inf
+ model: pix2pix [default: test]
+ n_layers_D: 3
+ name: rhino_pix2pix_roi [default: experiment_name]
+ ndf: 64
+ netD: basic
+ netG: unet_256
+ ngf: 64
+ no_dropout: False
+ no_flip: False
+ norm: batch
+ num_test: -1 [default: 50]
+ num_threads: 4
+ output_nc: 3
+ phase: test
+ preprocess: none [default: resize_and_crop]
+ results_dir: results/ep10 [default: ./results/]
+ serial_batches: False
+ suffix:
+ use_wandb: False
+ verbose: False
+ wandb_project_name: CycleGAN-and-pix2pix
+----------------- End -------------------
+Traceback (most recent call last):
+ File "test.py", line 54, in
+ dataset = create_dataset(opt) # create a dataset given opt.dataset_mode and other options
+ File "/data1/liutao/pix2pix/data/__init__.py", line 60, in create_dataset
+ data_loader = CustomDatasetDataLoader(opt)
+ File "/data1/liutao/pix2pix/data/__init__.py", line 76, in __init__
+ self.dataset = dataset_class(opt)
+ File "/data1/liutao/pix2pix/data/aligned_dataset.py", line 16, in __init__
+ self.AB_paths = sorted(make_dataset(self.dir_AB, opt.max_dataset_size))
+ File "/data1/liutao/pix2pix/data/image_folder.py", line 36, in make_dataset
+ assert dir_path.is_dir(), f"{dir} is not a valid directory"
+AssertionError: datasets/rhino_aligned/test is not a valid directory
+Traceback (most recent call last):
+ File "tools/evaluate.py", line 7, in
+ import torch, lpips
+ModuleNotFoundError: No module named 'lpips'
+[2025年 09月 17日 星期三 18:10:26 CST] 完成评估 epoch 10
+[2025年 09月 17日 星期三 18:17:26 CST] 评估 epoch 15
+----------------- Options ---------------
+ aspect_ratio: 1.0
+ batch_size: 1
+ checkpoints_dir: checkpoints [default: ./checkpoints]
+ crop_size: 256
+ dataroot: datasets/rhino_aligned [default: None]
+ dataset_mode: aligned
+ direction: AtoB
+ display_winsize: 256
+ epoch: 15 [default: latest]
+ eval: False
+ init_gain: 0.02
+ init_type: normal
+ input_nc: 3
+ isTrain: False [default: None]
+ lambda_roi: 0.0
+ load_iter: 0 [default: 0]
+ load_size: 256
+ masks_dir:
+ max_dataset_size: inf
+ model: pix2pix [default: test]
+ n_layers_D: 3
+ name: rhino_pix2pix_roi [default: experiment_name]
+ ndf: 64
+ netD: basic
+ netG: unet_256
+ ngf: 64
+ no_dropout: False
+ no_flip: False
+ norm: batch
+ num_test: -1 [default: 50]
+ num_threads: 4
+ output_nc: 3
+ phase: test
+ preprocess: none [default: resize_and_crop]
+ results_dir: results/ep15 [default: ./results/]
+ serial_batches: False
+ suffix:
+ use_wandb: False
+ verbose: False
+ wandb_project_name: CycleGAN-and-pix2pix
+----------------- End -------------------
+Traceback (most recent call last):
+ File "test.py", line 54, in
+ dataset = create_dataset(opt) # create a dataset given opt.dataset_mode and other options
+ File "/data1/liutao/pix2pix/data/__init__.py", line 60, in create_dataset
+ data_loader = CustomDatasetDataLoader(opt)
+ File "/data1/liutao/pix2pix/data/__init__.py", line 76, in __init__
+ self.dataset = dataset_class(opt)
+ File "/data1/liutao/pix2pix/data/aligned_dataset.py", line 16, in __init__
+ self.AB_paths = sorted(make_dataset(self.dir_AB, opt.max_dataset_size))
+ File "/data1/liutao/pix2pix/data/image_folder.py", line 36, in make_dataset
+ assert dir_path.is_dir(), f"{dir} is not a valid directory"
+AssertionError: datasets/rhino_aligned/test is not a valid directory
+Traceback (most recent call last):
+ File "tools/evaluate.py", line 7, in
+ import torch, lpips
+ModuleNotFoundError: No module named 'lpips'
+[2025年 09月 17日 星期三 18:17:29 CST] 完成评估 epoch 15
+[2025年 09月 17日 星期三 18:24:29 CST] 评估 epoch 20
+----------------- Options ---------------
+ aspect_ratio: 1.0
+ batch_size: 1
+ checkpoints_dir: checkpoints [default: ./checkpoints]
+ crop_size: 256
+ dataroot: datasets/rhino_aligned [default: None]
+ dataset_mode: aligned
+ direction: AtoB
+ display_winsize: 256
+ epoch: 20 [default: latest]
+ eval: False
+ init_gain: 0.02
+ init_type: normal
+ input_nc: 3
+ isTrain: False [default: None]
+ lambda_roi: 0.0
+ load_iter: 0 [default: 0]
+ load_size: 256
+ masks_dir:
+ max_dataset_size: inf
+ model: pix2pix [default: test]
+ n_layers_D: 3
+ name: rhino_pix2pix_roi [default: experiment_name]
+ ndf: 64
+ netD: basic
+ netG: unet_256
+ ngf: 64
+ no_dropout: False
+ no_flip: False
+ norm: batch
+ num_test: -1 [default: 50]
+ num_threads: 4
+ output_nc: 3
+ phase: test
+ preprocess: none [default: resize_and_crop]
+ results_dir: results/ep20 [default: ./results/]
+ serial_batches: False
+ suffix:
+ use_wandb: False
+ verbose: False
+ wandb_project_name: CycleGAN-and-pix2pix
+----------------- End -------------------
+Traceback (most recent call last):
+ File "test.py", line 54, in
+ dataset = create_dataset(opt) # create a dataset given opt.dataset_mode and other options
+ File "/data1/liutao/pix2pix/data/__init__.py", line 60, in create_dataset
+ data_loader = CustomDatasetDataLoader(opt)
+ File "/data1/liutao/pix2pix/data/__init__.py", line 76, in __init__
+ self.dataset = dataset_class(opt)
+ File "/data1/liutao/pix2pix/data/aligned_dataset.py", line 16, in __init__
+ self.AB_paths = sorted(make_dataset(self.dir_AB, opt.max_dataset_size))
+ File "/data1/liutao/pix2pix/data/image_folder.py", line 36, in make_dataset
+ assert dir_path.is_dir(), f"{dir} is not a valid directory"
+AssertionError: datasets/rhino_aligned/test is not a valid directory
+Traceback (most recent call last):
+ File "tools/evaluate.py", line 7, in
+ import torch, lpips
+ModuleNotFoundError: No module named 'lpips'
+[2025年 09月 17日 星期三 18:24:33 CST] 完成评估 epoch 20
+[2025年 09月 17日 星期三 18:32:33 CST] 评估 epoch 25
+----------------- Options ---------------
+ aspect_ratio: 1.0
+ batch_size: 1
+ checkpoints_dir: checkpoints [default: ./checkpoints]
+ crop_size: 256
+ dataroot: datasets/rhino_aligned [default: None]
+ dataset_mode: aligned
+ direction: AtoB
+ display_winsize: 256
+ epoch: 25 [default: latest]
+ eval: False
+ init_gain: 0.02
+ init_type: normal
+ input_nc: 3
+ isTrain: False [default: None]
+ lambda_roi: 0.0
+ load_iter: 0 [default: 0]
+ load_size: 256
+ masks_dir:
+ max_dataset_size: inf
+ model: pix2pix [default: test]
+ n_layers_D: 3
+ name: rhino_pix2pix_roi [default: experiment_name]
+ ndf: 64
+ netD: basic
+ netG: unet_256
+ ngf: 64
+ no_dropout: False
+ no_flip: False
+ norm: batch
+ num_test: -1 [default: 50]
+ num_threads: 4
+ output_nc: 3
+ phase: test
+ preprocess: none [default: resize_and_crop]
+ results_dir: results/ep25 [default: ./results/]
+ serial_batches: False
+ suffix:
+ use_wandb: False
+ verbose: False
+ wandb_project_name: CycleGAN-and-pix2pix
+----------------- End -------------------
+Traceback (most recent call last):
+ File "test.py", line 54, in
+ dataset = create_dataset(opt) # create a dataset given opt.dataset_mode and other options
+ File "/data1/liutao/pix2pix/data/__init__.py", line 60, in create_dataset
+ data_loader = CustomDatasetDataLoader(opt)
+ File "/data1/liutao/pix2pix/data/__init__.py", line 76, in __init__
+ self.dataset = dataset_class(opt)
+ File "/data1/liutao/pix2pix/data/aligned_dataset.py", line 16, in __init__
+ self.AB_paths = sorted(make_dataset(self.dir_AB, opt.max_dataset_size))
+ File "/data1/liutao/pix2pix/data/image_folder.py", line 36, in make_dataset
+ assert dir_path.is_dir(), f"{dir} is not a valid directory"
+AssertionError: datasets/rhino_aligned/test is not a valid directory
+Traceback (most recent call last):
+ File "tools/evaluate.py", line 7, in
+ import torch, lpips
+ModuleNotFoundError: No module named 'lpips'
+[2025年 09月 17日 星期三 18:32:36 CST] 完成评估 epoch 25
+[2025年 09月 17日 星期三 18:39:36 CST] 评估 epoch 30
+----------------- Options ---------------
+ aspect_ratio: 1.0
+ batch_size: 1
+ checkpoints_dir: checkpoints [default: ./checkpoints]
+ crop_size: 256
+ dataroot: datasets/rhino_aligned [default: None]
+ dataset_mode: aligned
+ direction: AtoB
+ display_winsize: 256
+ epoch: 30 [default: latest]
+ eval: False
+ init_gain: 0.02
+ init_type: normal
+ input_nc: 3
+ isTrain: False [default: None]
+ lambda_roi: 0.0
+ load_iter: 0 [default: 0]
+ load_size: 256
+ masks_dir:
+ max_dataset_size: inf
+ model: pix2pix [default: test]
+ n_layers_D: 3
+ name: rhino_pix2pix_roi [default: experiment_name]
+ ndf: 64
+ netD: basic
+ netG: unet_256
+ ngf: 64
+ no_dropout: False
+ no_flip: False
+ norm: batch
+ num_test: -1 [default: 50]
+ num_threads: 4
+ output_nc: 3
+ phase: test
+ preprocess: none [default: resize_and_crop]
+ results_dir: results/ep30 [default: ./results/]
+ serial_batches: False
+ suffix:
+ use_wandb: False
+ verbose: False
+ wandb_project_name: CycleGAN-and-pix2pix
+----------------- End -------------------
+Traceback (most recent call last):
+ File "test.py", line 54, in
+ dataset = create_dataset(opt) # create a dataset given opt.dataset_mode and other options
+ File "/data1/liutao/pix2pix/data/__init__.py", line 60, in create_dataset
+ data_loader = CustomDatasetDataLoader(opt)
+ File "/data1/liutao/pix2pix/data/__init__.py", line 76, in __init__
+ self.dataset = dataset_class(opt)
+ File "/data1/liutao/pix2pix/data/aligned_dataset.py", line 16, in __init__
+ self.AB_paths = sorted(make_dataset(self.dir_AB, opt.max_dataset_size))
+ File "/data1/liutao/pix2pix/data/image_folder.py", line 36, in make_dataset
+ assert dir_path.is_dir(), f"{dir} is not a valid directory"
+AssertionError: datasets/rhino_aligned/test is not a valid directory
+Traceback (most recent call last):
+ File "tools/evaluate.py", line 7, in
+ import torch, lpips
+ModuleNotFoundError: No module named 'lpips'
+[2025年 09月 17日 星期三 18:39:39 CST] 完成评估 epoch 30
+[2025年 09月 17日 星期三 18:46:39 CST] 评估 epoch 35
+----------------- Options ---------------
+ aspect_ratio: 1.0
+ batch_size: 1
+ checkpoints_dir: checkpoints [default: ./checkpoints]
+ crop_size: 256
+ dataroot: datasets/rhino_aligned [default: None]
+ dataset_mode: aligned
+ direction: AtoB
+ display_winsize: 256
+ epoch: 35 [default: latest]
+ eval: False
+ init_gain: 0.02
+ init_type: normal
+ input_nc: 3
+ isTrain: False [default: None]
+ lambda_roi: 0.0
+ load_iter: 0 [default: 0]
+ load_size: 256
+ masks_dir:
+ max_dataset_size: inf
+ model: pix2pix [default: test]
+ n_layers_D: 3
+ name: rhino_pix2pix_roi [default: experiment_name]
+ ndf: 64
+ netD: basic
+ netG: unet_256
+ ngf: 64
+ no_dropout: False
+ no_flip: False
+ norm: batch
+ num_test: -1 [default: 50]
+ num_threads: 4
+ output_nc: 3
+ phase: test
+ preprocess: none [default: resize_and_crop]
+ results_dir: results/ep35 [default: ./results/]
+ serial_batches: False
+ suffix:
+ use_wandb: False
+ verbose: False
+ wandb_project_name: CycleGAN-and-pix2pix
+----------------- End -------------------
+Traceback (most recent call last):
+ File "test.py", line 54, in
+ dataset = create_dataset(opt) # create a dataset given opt.dataset_mode and other options
+ File "/data1/liutao/pix2pix/data/__init__.py", line 60, in create_dataset
+ data_loader = CustomDatasetDataLoader(opt)
+ File "/data1/liutao/pix2pix/data/__init__.py", line 76, in __init__
+ self.dataset = dataset_class(opt)
+ File "/data1/liutao/pix2pix/data/aligned_dataset.py", line 16, in __init__
+ self.AB_paths = sorted(make_dataset(self.dir_AB, opt.max_dataset_size))
+ File "/data1/liutao/pix2pix/data/image_folder.py", line 36, in make_dataset
+ assert dir_path.is_dir(), f"{dir} is not a valid directory"
+AssertionError: datasets/rhino_aligned/test is not a valid directory
+Traceback (most recent call last):
+ File "tools/evaluate.py", line 7, in
+ import torch, lpips
+ModuleNotFoundError: No module named 'lpips'
+[2025年 09月 17日 星期三 18:46:43 CST] 完成评估 epoch 35
+[2025年 09月 17日 星期三 18:54:43 CST] 评估 epoch 40
+----------------- Options ---------------
+ aspect_ratio: 1.0
+ batch_size: 1
+ checkpoints_dir: checkpoints [default: ./checkpoints]
+ crop_size: 256
+ dataroot: datasets/rhino_aligned [default: None]
+ dataset_mode: aligned
+ direction: AtoB
+ display_winsize: 256
+ epoch: 40 [default: latest]
+ eval: False
+ init_gain: 0.02
+ init_type: normal
+ input_nc: 3
+ isTrain: False [default: None]
+ lambda_roi: 0.0
+ load_iter: 0 [default: 0]
+ load_size: 256
+ masks_dir:
+ max_dataset_size: inf
+ model: pix2pix [default: test]
+ n_layers_D: 3
+ name: rhino_pix2pix_roi [default: experiment_name]
+ ndf: 64
+ netD: basic
+ netG: unet_256
+ ngf: 64
+ no_dropout: False
+ no_flip: False
+ norm: batch
+ num_test: -1 [default: 50]
+ num_threads: 4
+ output_nc: 3
+ phase: test
+ preprocess: none [default: resize_and_crop]
+ results_dir: results/ep40 [default: ./results/]
+ serial_batches: False
+ suffix:
+ use_wandb: False
+ verbose: False
+ wandb_project_name: CycleGAN-and-pix2pix
+----------------- End -------------------
+Traceback (most recent call last):
+ File "test.py", line 54, in
+ dataset = create_dataset(opt) # create a dataset given opt.dataset_mode and other options
+ File "/data1/liutao/pix2pix/data/__init__.py", line 60, in create_dataset
+ data_loader = CustomDatasetDataLoader(opt)
+ File "/data1/liutao/pix2pix/data/__init__.py", line 76, in __init__
+ self.dataset = dataset_class(opt)
+ File "/data1/liutao/pix2pix/data/aligned_dataset.py", line 16, in __init__
+ self.AB_paths = sorted(make_dataset(self.dir_AB, opt.max_dataset_size))
+ File "/data1/liutao/pix2pix/data/image_folder.py", line 36, in make_dataset
+ assert dir_path.is_dir(), f"{dir} is not a valid directory"
+AssertionError: datasets/rhino_aligned/test is not a valid directory
+Traceback (most recent call last):
+ File "tools/evaluate.py", line 7, in
+ import torch, lpips
+ModuleNotFoundError: No module named 'lpips'
+[2025年 09月 17日 星期三 18:54:46 CST] 完成评估 epoch 40
+[2025年 09月 17日 星期三 19:01:46 CST] 评估 epoch 45
+----------------- Options ---------------
+ aspect_ratio: 1.0
+ batch_size: 1
+ checkpoints_dir: checkpoints [default: ./checkpoints]
+ crop_size: 256
+ dataroot: datasets/rhino_aligned [default: None]
+ dataset_mode: aligned
+ direction: AtoB
+ display_winsize: 256
+ epoch: 45 [default: latest]
+ eval: False
+ init_gain: 0.02
+ init_type: normal
+ input_nc: 3
+ isTrain: False [default: None]
+ lambda_roi: 0.0
+ load_iter: 0 [default: 0]
+ load_size: 256
+ masks_dir:
+ max_dataset_size: inf
+ model: pix2pix [default: test]
+ n_layers_D: 3
+ name: rhino_pix2pix_roi [default: experiment_name]
+ ndf: 64
+ netD: basic
+ netG: unet_256
+ ngf: 64
+ no_dropout: False
+ no_flip: False
+ norm: batch
+ num_test: -1 [default: 50]
+ num_threads: 4
+ output_nc: 3
+ phase: test
+ preprocess: none [default: resize_and_crop]
+ results_dir: results/ep45 [default: ./results/]
+ serial_batches: False
+ suffix:
+ use_wandb: False
+ verbose: False
+ wandb_project_name: CycleGAN-and-pix2pix
+----------------- End -------------------
+Traceback (most recent call last):
+ File "test.py", line 54, in
+ dataset = create_dataset(opt) # create a dataset given opt.dataset_mode and other options
+ File "/data1/liutao/pix2pix/data/__init__.py", line 60, in create_dataset
+ data_loader = CustomDatasetDataLoader(opt)
+ File "/data1/liutao/pix2pix/data/__init__.py", line 76, in __init__
+ self.dataset = dataset_class(opt)
+ File "/data1/liutao/pix2pix/data/aligned_dataset.py", line 16, in __init__
+ self.AB_paths = sorted(make_dataset(self.dir_AB, opt.max_dataset_size))
+ File "/data1/liutao/pix2pix/data/image_folder.py", line 36, in make_dataset
+ assert dir_path.is_dir(), f"{dir} is not a valid directory"
+AssertionError: datasets/rhino_aligned/test is not a valid directory
+Traceback (most recent call last):
+ File "tools/evaluate.py", line 7, in
+ import torch, lpips
+ModuleNotFoundError: No module named 'lpips'
+[2025年 09月 17日 星期三 19:01:50 CST] 完成评估 epoch 45
+[2025年 09月 17日 星期三 19:08:50 CST] 评估 epoch 50
+----------------- Options ---------------
+ aspect_ratio: 1.0
+ batch_size: 1
+ checkpoints_dir: checkpoints [default: ./checkpoints]
+ crop_size: 256
+ dataroot: datasets/rhino_aligned [default: None]
+ dataset_mode: aligned
+ direction: AtoB
+ display_winsize: 256
+ epoch: 50 [default: latest]
+ eval: False
+ init_gain: 0.02
+ init_type: normal
+ input_nc: 3
+ isTrain: False [default: None]
+ lambda_roi: 0.0
+ load_iter: 0 [default: 0]
+ load_size: 256
+ masks_dir:
+ max_dataset_size: inf
+ model: pix2pix [default: test]
+ n_layers_D: 3
+ name: rhino_pix2pix_roi [default: experiment_name]
+ ndf: 64
+ netD: basic
+ netG: unet_256
+ ngf: 64
+ no_dropout: False
+ no_flip: False
+ norm: batch
+ num_test: -1 [default: 50]
+ num_threads: 4
+ output_nc: 3
+ phase: test
+ preprocess: none [default: resize_and_crop]
+ results_dir: results/ep50 [default: ./results/]
+ serial_batches: False
+ suffix:
+ use_wandb: False
+ verbose: False
+ wandb_project_name: CycleGAN-and-pix2pix
+----------------- End -------------------
+Traceback (most recent call last):
+ File "test.py", line 54, in
+ dataset = create_dataset(opt) # create a dataset given opt.dataset_mode and other options
+ File "/data1/liutao/pix2pix/data/__init__.py", line 60, in create_dataset
+ data_loader = CustomDatasetDataLoader(opt)
+ File "/data1/liutao/pix2pix/data/__init__.py", line 76, in __init__
+ self.dataset = dataset_class(opt)
+ File "/data1/liutao/pix2pix/data/aligned_dataset.py", line 16, in __init__
+ self.AB_paths = sorted(make_dataset(self.dir_AB, opt.max_dataset_size))
+ File "/data1/liutao/pix2pix/data/image_folder.py", line 36, in make_dataset
+ assert dir_path.is_dir(), f"{dir} is not a valid directory"
+AssertionError: datasets/rhino_aligned/test is not a valid directory
+Traceback (most recent call last):
+ File "tools/evaluate.py", line 7, in
+ import torch, lpips
+ModuleNotFoundError: No module named 'lpips'
+[2025年 09月 17日 星期三 19:08:53 CST] 完成评估 epoch 50
+[2025年 09月 17日 星期三 19:15:53 CST] 评估 epoch 55
+----------------- Options ---------------
+ aspect_ratio: 1.0
+ batch_size: 1
+ checkpoints_dir: checkpoints [default: ./checkpoints]
+ crop_size: 256
+ dataroot: datasets/rhino_aligned [default: None]
+ dataset_mode: aligned
+ direction: AtoB
+ display_winsize: 256
+ epoch: 55 [default: latest]
+ eval: False
+ init_gain: 0.02
+ init_type: normal
+ input_nc: 3
+ isTrain: False [default: None]
+ lambda_roi: 0.0
+ load_iter: 0 [default: 0]
+ load_size: 256
+ masks_dir:
+ max_dataset_size: inf
+ model: pix2pix [default: test]
+ n_layers_D: 3
+ name: rhino_pix2pix_roi [default: experiment_name]
+ ndf: 64
+ netD: basic
+ netG: unet_256
+ ngf: 64
+ no_dropout: False
+ no_flip: False
+ norm: batch
+ num_test: -1 [default: 50]
+ num_threads: 4
+ output_nc: 3
+ phase: test
+ preprocess: none [default: resize_and_crop]
+ results_dir: results/ep55 [default: ./results/]
+ serial_batches: False
+ suffix:
+ use_wandb: False
+ verbose: False
+ wandb_project_name: CycleGAN-and-pix2pix
+----------------- End -------------------
+Traceback (most recent call last):
+ File "test.py", line 54, in
+ dataset = create_dataset(opt) # create a dataset given opt.dataset_mode and other options
+ File "/data1/liutao/pix2pix/data/__init__.py", line 60, in create_dataset
+ data_loader = CustomDatasetDataLoader(opt)
+ File "/data1/liutao/pix2pix/data/__init__.py", line 76, in __init__
+ self.dataset = dataset_class(opt)
+ File "/data1/liutao/pix2pix/data/aligned_dataset.py", line 16, in __init__
+ self.AB_paths = sorted(make_dataset(self.dir_AB, opt.max_dataset_size))
+ File "/data1/liutao/pix2pix/data/image_folder.py", line 36, in make_dataset
+ assert dir_path.is_dir(), f"{dir} is not a valid directory"
+AssertionError: datasets/rhino_aligned/test is not a valid directory
+Traceback (most recent call last):
+ File "tools/evaluate.py", line 7, in
+ import torch, lpips
+ModuleNotFoundError: No module named 'lpips'
+[2025年 09月 17日 星期三 19:15:56 CST] 完成评估 epoch 55
+[2025年 09月 17日 星期三 19:23:56 CST] 评估 epoch 60
+----------------- Options ---------------
+ aspect_ratio: 1.0
+ batch_size: 1
+ checkpoints_dir: checkpoints [default: ./checkpoints]
+ crop_size: 256
+ dataroot: datasets/rhino_aligned [default: None]
+ dataset_mode: aligned
+ direction: AtoB
+ display_winsize: 256
+ epoch: 60 [default: latest]
+ eval: False
+ init_gain: 0.02
+ init_type: normal
+ input_nc: 3
+ isTrain: False [default: None]
+ lambda_roi: 0.0
+ load_iter: 0 [default: 0]
+ load_size: 256
+ masks_dir:
+ max_dataset_size: inf
+ model: pix2pix [default: test]
+ n_layers_D: 3
+ name: rhino_pix2pix_roi [default: experiment_name]
+ ndf: 64
+ netD: basic
+ netG: unet_256
+ ngf: 64
+ no_dropout: False
+ no_flip: False
+ norm: batch
+ num_test: -1 [default: 50]
+ num_threads: 4
+ output_nc: 3
+ phase: test
+ preprocess: none [default: resize_and_crop]
+ results_dir: results/ep60 [default: ./results/]
+ serial_batches: False
+ suffix:
+ use_wandb: False
+ verbose: False
+ wandb_project_name: CycleGAN-and-pix2pix
+----------------- End -------------------
+Traceback (most recent call last):
+ File "test.py", line 54, in
+ dataset = create_dataset(opt) # create a dataset given opt.dataset_mode and other options
+ File "/data1/liutao/pix2pix/data/__init__.py", line 60, in create_dataset
+ data_loader = CustomDatasetDataLoader(opt)
+ File "/data1/liutao/pix2pix/data/__init__.py", line 76, in __init__
+ self.dataset = dataset_class(opt)
+ File "/data1/liutao/pix2pix/data/aligned_dataset.py", line 16, in __init__
+ self.AB_paths = sorted(make_dataset(self.dir_AB, opt.max_dataset_size))
+ File "/data1/liutao/pix2pix/data/image_folder.py", line 36, in make_dataset
+ assert dir_path.is_dir(), f"{dir} is not a valid directory"
+AssertionError: datasets/rhino_aligned/test is not a valid directory
+Traceback (most recent call last):
+ File "tools/evaluate.py", line 7, in
+ import torch, lpips
+ModuleNotFoundError: No module named 'lpips'
+[2025年 09月 17日 星期三 19:24:00 CST] 完成评估 epoch 60
+[2025年 09月 17日 星期三 19:31:00 CST] 评估 epoch 65
+----------------- Options ---------------
+ aspect_ratio: 1.0
+ batch_size: 1
+ checkpoints_dir: checkpoints [default: ./checkpoints]
+ crop_size: 256
+ dataroot: datasets/rhino_aligned [default: None]
+ dataset_mode: aligned
+ direction: AtoB
+ display_winsize: 256
+ epoch: 65 [default: latest]
+ eval: False
+ init_gain: 0.02
+ init_type: normal
+ input_nc: 3
+ isTrain: False [default: None]
+ lambda_roi: 0.0
+ load_iter: 0 [default: 0]
+ load_size: 256
+ masks_dir:
+ max_dataset_size: inf
+ model: pix2pix [default: test]
+ n_layers_D: 3
+ name: rhino_pix2pix_roi [default: experiment_name]
+ ndf: 64
+ netD: basic
+ netG: unet_256
+ ngf: 64
+ no_dropout: False
+ no_flip: False
+ norm: batch
+ num_test: -1 [default: 50]
+ num_threads: 4
+ output_nc: 3
+ phase: test
+ preprocess: none [default: resize_and_crop]
+ results_dir: results/ep65 [default: ./results/]
+ serial_batches: False
+ suffix:
+ use_wandb: False
+ verbose: False
+ wandb_project_name: CycleGAN-and-pix2pix
+----------------- End -------------------
+Traceback (most recent call last):
+ File "test.py", line 54, in
+ dataset = create_dataset(opt) # create a dataset given opt.dataset_mode and other options
+ File "/data1/liutao/pix2pix/data/__init__.py", line 60, in create_dataset
+ data_loader = CustomDatasetDataLoader(opt)
+ File "/data1/liutao/pix2pix/data/__init__.py", line 76, in __init__
+ self.dataset = dataset_class(opt)
+ File "/data1/liutao/pix2pix/data/aligned_dataset.py", line 16, in __init__
+ self.AB_paths = sorted(make_dataset(self.dir_AB, opt.max_dataset_size))
+ File "/data1/liutao/pix2pix/data/image_folder.py", line 36, in make_dataset
+ assert dir_path.is_dir(), f"{dir} is not a valid directory"
+AssertionError: datasets/rhino_aligned/test is not a valid directory
+Traceback (most recent call last):
+ File "tools/evaluate.py", line 7, in
+ import torch, lpips
+ModuleNotFoundError: No module named 'lpips'
+[2025年 09月 17日 星期三 19:31:03 CST] 完成评估 epoch 65
+[2025年 09月 17日 星期三 19:38:03 CST] 评估 epoch 70
+----------------- Options ---------------
+ aspect_ratio: 1.0
+ batch_size: 1
+ checkpoints_dir: checkpoints [default: ./checkpoints]
+ crop_size: 256
+ dataroot: datasets/rhino_aligned [default: None]
+ dataset_mode: aligned
+ direction: AtoB
+ display_winsize: 256
+ epoch: 70 [default: latest]
+ eval: False
+ init_gain: 0.02
+ init_type: normal
+ input_nc: 3
+ isTrain: False [default: None]
+ lambda_roi: 0.0
+ load_iter: 0 [default: 0]
+ load_size: 256
+ masks_dir:
+ max_dataset_size: inf
+ model: pix2pix [default: test]
+ n_layers_D: 3
+ name: rhino_pix2pix_roi [default: experiment_name]
+ ndf: 64
+ netD: basic
+ netG: unet_256
+ ngf: 64
+ no_dropout: False
+ no_flip: False
+ norm: batch
+ num_test: -1 [default: 50]
+ num_threads: 4
+ output_nc: 3
+ phase: test
+ preprocess: none [default: resize_and_crop]
+ results_dir: results/ep70 [default: ./results/]
+ serial_batches: False
+ suffix:
+ use_wandb: False
+ verbose: False
+ wandb_project_name: CycleGAN-and-pix2pix
+----------------- End -------------------
+Traceback (most recent call last):
+ File "test.py", line 54, in
+ dataset = create_dataset(opt) # create a dataset given opt.dataset_mode and other options
+ File "/data1/liutao/pix2pix/data/__init__.py", line 60, in create_dataset
+ data_loader = CustomDatasetDataLoader(opt)
+ File "/data1/liutao/pix2pix/data/__init__.py", line 76, in __init__
+ self.dataset = dataset_class(opt)
+ File "/data1/liutao/pix2pix/data/aligned_dataset.py", line 16, in __init__
+ self.AB_paths = sorted(make_dataset(self.dir_AB, opt.max_dataset_size))
+ File "/data1/liutao/pix2pix/data/image_folder.py", line 36, in make_dataset
+ assert dir_path.is_dir(), f"{dir} is not a valid directory"
+AssertionError: datasets/rhino_aligned/test is not a valid directory
+Traceback (most recent call last):
+ File "tools/evaluate.py", line 7, in
+ import torch, lpips
+ModuleNotFoundError: No module named 'lpips'
+[2025年 09月 17日 星期三 19:38:06 CST] 完成评估 epoch 70
+[2025年 09月 17日 星期三 19:46:06 CST] 评估 epoch 75
+----------------- Options ---------------
+ aspect_ratio: 1.0
+ batch_size: 1
+ checkpoints_dir: checkpoints [default: ./checkpoints]
+ crop_size: 256
+ dataroot: datasets/rhino_aligned [default: None]
+ dataset_mode: aligned
+ direction: AtoB
+ display_winsize: 256
+ epoch: 75 [default: latest]
+ eval: False
+ init_gain: 0.02
+ init_type: normal
+ input_nc: 3
+ isTrain: False [default: None]
+ lambda_roi: 0.0
+ load_iter: 0 [default: 0]
+ load_size: 256
+ masks_dir:
+ max_dataset_size: inf
+ model: pix2pix [default: test]
+ n_layers_D: 3
+ name: rhino_pix2pix_roi [default: experiment_name]
+ ndf: 64
+ netD: basic
+ netG: unet_256
+ ngf: 64
+ no_dropout: False
+ no_flip: False
+ norm: batch
+ num_test: -1 [default: 50]
+ num_threads: 4
+ output_nc: 3
+ phase: test
+ preprocess: none [default: resize_and_crop]
+ results_dir: results/ep75 [default: ./results/]
+ serial_batches: False
+ suffix:
+ use_wandb: False
+ verbose: False
+ wandb_project_name: CycleGAN-and-pix2pix
+----------------- End -------------------
+Traceback (most recent call last):
+ File "test.py", line 54, in
+ dataset = create_dataset(opt) # create a dataset given opt.dataset_mode and other options
+ File "/data1/liutao/pix2pix/data/__init__.py", line 60, in create_dataset
+ data_loader = CustomDatasetDataLoader(opt)
+ File "/data1/liutao/pix2pix/data/__init__.py", line 76, in __init__
+ self.dataset = dataset_class(opt)
+ File "/data1/liutao/pix2pix/data/aligned_dataset.py", line 16, in __init__
+ self.AB_paths = sorted(make_dataset(self.dir_AB, opt.max_dataset_size))
+ File "/data1/liutao/pix2pix/data/image_folder.py", line 36, in make_dataset
+ assert dir_path.is_dir(), f"{dir} is not a valid directory"
+AssertionError: datasets/rhino_aligned/test is not a valid directory
+Traceback (most recent call last):
+ File "tools/evaluate.py", line 7, in
+ import torch, lpips
+ModuleNotFoundError: No module named 'lpips'
+[2025年 09月 17日 星期三 19:46:10 CST] 完成评估 epoch 75
+[2025年 09月 17日 星期三 19:53:10 CST] 评估 epoch 80
+----------------- Options ---------------
+ aspect_ratio: 1.0
+ batch_size: 1
+ checkpoints_dir: checkpoints [default: ./checkpoints]
+ crop_size: 256
+ dataroot: datasets/rhino_aligned [default: None]
+ dataset_mode: aligned
+ direction: AtoB
+ display_winsize: 256
+ epoch: 80 [default: latest]
+ eval: False
+ init_gain: 0.02
+ init_type: normal
+ input_nc: 3
+ isTrain: False [default: None]
+ lambda_roi: 0.0
+ load_iter: 0 [default: 0]
+ load_size: 256
+ masks_dir:
+ max_dataset_size: inf
+ model: pix2pix [default: test]
+ n_layers_D: 3
+ name: rhino_pix2pix_roi [default: experiment_name]
+ ndf: 64
+ netD: basic
+ netG: unet_256
+ ngf: 64
+ no_dropout: False
+ no_flip: False
+ norm: batch
+ num_test: -1 [default: 50]
+ num_threads: 4
+ output_nc: 3
+ phase: test
+ preprocess: none [default: resize_and_crop]
+ results_dir: results/ep80 [default: ./results/]
+ serial_batches: False
+ suffix:
+ use_wandb: False
+ verbose: False
+ wandb_project_name: CycleGAN-and-pix2pix
+----------------- End -------------------
+Traceback (most recent call last):
+ File "test.py", line 54, in
+ dataset = create_dataset(opt) # create a dataset given opt.dataset_mode and other options
+ File "/data1/liutao/pix2pix/data/__init__.py", line 60, in create_dataset
+ data_loader = CustomDatasetDataLoader(opt)
+ File "/data1/liutao/pix2pix/data/__init__.py", line 76, in __init__
+ self.dataset = dataset_class(opt)
+ File "/data1/liutao/pix2pix/data/aligned_dataset.py", line 16, in __init__
+ self.AB_paths = sorted(make_dataset(self.dir_AB, opt.max_dataset_size))
+ File "/data1/liutao/pix2pix/data/image_folder.py", line 36, in make_dataset
+ assert dir_path.is_dir(), f"{dir} is not a valid directory"
+AssertionError: datasets/rhino_aligned/test is not a valid directory
+Traceback (most recent call last):
+ File "tools/evaluate.py", line 7, in
+ import torch, lpips
+ModuleNotFoundError: No module named 'lpips'
+[2025年 09月 17日 星期三 19:53:13 CST] 完成评估 epoch 80
+[2025年 09月 17日 星期三 20:00:13 CST] 评估 epoch 85
+----------------- Options ---------------
+ aspect_ratio: 1.0
+ batch_size: 1
+ checkpoints_dir: checkpoints [default: ./checkpoints]
+ crop_size: 256
+ dataroot: datasets/rhino_aligned [default: None]
+ dataset_mode: aligned
+ direction: AtoB
+ display_winsize: 256
+ epoch: 85 [default: latest]
+ eval: False
+ init_gain: 0.02
+ init_type: normal
+ input_nc: 3
+ isTrain: False [default: None]
+ lambda_roi: 0.0
+ load_iter: 0 [default: 0]
+ load_size: 256
+ masks_dir:
+ max_dataset_size: inf
+ model: pix2pix [default: test]
+ n_layers_D: 3
+ name: rhino_pix2pix_roi [default: experiment_name]
+ ndf: 64
+ netD: basic
+ netG: unet_256
+ ngf: 64
+ no_dropout: False
+ no_flip: False
+ norm: batch
+ num_test: -1 [default: 50]
+ num_threads: 4
+ output_nc: 3
+ phase: test
+ preprocess: none [default: resize_and_crop]
+ results_dir: results/ep85 [default: ./results/]
+ serial_batches: False
+ suffix:
+ use_wandb: False
+ verbose: False
+ wandb_project_name: CycleGAN-and-pix2pix
+----------------- End -------------------
+Traceback (most recent call last):
+ File "test.py", line 54, in
+ dataset = create_dataset(opt) # create a dataset given opt.dataset_mode and other options
+ File "/data1/liutao/pix2pix/data/__init__.py", line 60, in create_dataset
+ data_loader = CustomDatasetDataLoader(opt)
+ File "/data1/liutao/pix2pix/data/__init__.py", line 76, in __init__
+ self.dataset = dataset_class(opt)
+ File "/data1/liutao/pix2pix/data/aligned_dataset.py", line 16, in __init__
+ self.AB_paths = sorted(make_dataset(self.dir_AB, opt.max_dataset_size))
+ File "/data1/liutao/pix2pix/data/image_folder.py", line 36, in make_dataset
+ assert dir_path.is_dir(), f"{dir} is not a valid directory"
+AssertionError: datasets/rhino_aligned/test is not a valid directory
+Traceback (most recent call last):
+ File "tools/evaluate.py", line 7, in
+ import torch, lpips
+ModuleNotFoundError: No module named 'lpips'
+[2025年 09月 17日 星期三 20:00:16 CST] 完成评估 epoch 85
+[2025年 09月 17日 星期三 20:07:16 CST] 评估 epoch 90
+----------------- Options ---------------
+ aspect_ratio: 1.0
+ batch_size: 1
+ checkpoints_dir: checkpoints [default: ./checkpoints]
+ crop_size: 256
+ dataroot: datasets/rhino_aligned [default: None]
+ dataset_mode: aligned
+ direction: AtoB
+ display_winsize: 256
+ epoch: 90 [default: latest]
+ eval: False
+ init_gain: 0.02
+ init_type: normal
+ input_nc: 3
+ isTrain: False [default: None]
+ lambda_roi: 0.0
+ load_iter: 0 [default: 0]
+ load_size: 256
+ masks_dir:
+ max_dataset_size: inf
+ model: pix2pix [default: test]
+ n_layers_D: 3
+ name: rhino_pix2pix_roi [default: experiment_name]
+ ndf: 64
+ netD: basic
+ netG: unet_256
+ ngf: 64
+ no_dropout: False
+ no_flip: False
+ norm: batch
+ num_test: -1 [default: 50]
+ num_threads: 4
+ output_nc: 3
+ phase: test
+ preprocess: none [default: resize_and_crop]
+ results_dir: results/ep90 [default: ./results/]
+ serial_batches: False
+ suffix:
+ use_wandb: False
+ verbose: False
+ wandb_project_name: CycleGAN-and-pix2pix
+----------------- End -------------------
+Traceback (most recent call last):
+ File "test.py", line 54, in
+ dataset = create_dataset(opt) # create a dataset given opt.dataset_mode and other options
+ File "/data1/liutao/pix2pix/data/__init__.py", line 60, in create_dataset
+ data_loader = CustomDatasetDataLoader(opt)
+ File "/data1/liutao/pix2pix/data/__init__.py", line 76, in __init__
+ self.dataset = dataset_class(opt)
+ File "/data1/liutao/pix2pix/data/aligned_dataset.py", line 16, in __init__
+ self.AB_paths = sorted(make_dataset(self.dir_AB, opt.max_dataset_size))
+ File "/data1/liutao/pix2pix/data/image_folder.py", line 36, in make_dataset
+ assert dir_path.is_dir(), f"{dir} is not a valid directory"
+AssertionError: datasets/rhino_aligned/test is not a valid directory
+Traceback (most recent call last):
+ File "tools/evaluate.py", line 7, in
+ import torch, lpips
+ModuleNotFoundError: No module named 'lpips'
+[2025年 09月 17日 星期三 20:07:20 CST] 完成评估 epoch 90
+[2025年 09月 17日 星期三 20:15:20 CST] 评估 epoch 95
+----------------- Options ---------------
+ aspect_ratio: 1.0
+ batch_size: 1
+ checkpoints_dir: checkpoints [default: ./checkpoints]
+ crop_size: 256
+ dataroot: datasets/rhino_aligned [default: None]
+ dataset_mode: aligned
+ direction: AtoB
+ display_winsize: 256
+ epoch: 95 [default: latest]
+ eval: False
+ init_gain: 0.02
+ init_type: normal
+ input_nc: 3
+ isTrain: False [default: None]
+ lambda_roi: 0.0
+ load_iter: 0 [default: 0]
+ load_size: 256
+ masks_dir:
+ max_dataset_size: inf
+ model: pix2pix [default: test]
+ n_layers_D: 3
+ name: rhino_pix2pix_roi [default: experiment_name]
+ ndf: 64
+ netD: basic
+ netG: unet_256
+ ngf: 64
+ no_dropout: False
+ no_flip: False
+ norm: batch
+ num_test: -1 [default: 50]
+ num_threads: 4
+ output_nc: 3
+ phase: test
+ preprocess: none [default: resize_and_crop]
+ results_dir: results/ep95 [default: ./results/]
+ serial_batches: False
+ suffix:
+ use_wandb: False
+ verbose: False
+ wandb_project_name: CycleGAN-and-pix2pix
+----------------- End -------------------
+Traceback (most recent call last):
+ File "test.py", line 54, in
+ dataset = create_dataset(opt) # create a dataset given opt.dataset_mode and other options
+ File "/data1/liutao/pix2pix/data/__init__.py", line 60, in create_dataset
+ data_loader = CustomDatasetDataLoader(opt)
+ File "/data1/liutao/pix2pix/data/__init__.py", line 76, in __init__
+ self.dataset = dataset_class(opt)
+ File "/data1/liutao/pix2pix/data/aligned_dataset.py", line 16, in __init__
+ self.AB_paths = sorted(make_dataset(self.dir_AB, opt.max_dataset_size))
+ File "/data1/liutao/pix2pix/data/image_folder.py", line 36, in make_dataset
+ assert dir_path.is_dir(), f"{dir} is not a valid directory"
+AssertionError: datasets/rhino_aligned/test is not a valid directory
+Traceback (most recent call last):
+ File "tools/evaluate.py", line 7, in
+ import torch, lpips
+ModuleNotFoundError: No module named 'lpips'
+[2025年 09月 17日 星期三 20:15:23 CST] 完成评估 epoch 95
+[2025年 09月 17日 星期三 20:22:23 CST] 评估 epoch 100
+----------------- Options ---------------
+ aspect_ratio: 1.0
+ batch_size: 1
+ checkpoints_dir: checkpoints [default: ./checkpoints]
+ crop_size: 256
+ dataroot: datasets/rhino_aligned [default: None]
+ dataset_mode: aligned
+ direction: AtoB
+ display_winsize: 256
+ epoch: 100 [default: latest]
+ eval: False
+ init_gain: 0.02
+ init_type: normal
+ input_nc: 3
+ isTrain: False [default: None]
+ lambda_roi: 0.0
+ load_iter: 0 [default: 0]
+ load_size: 256
+ masks_dir:
+ max_dataset_size: inf
+ model: pix2pix [default: test]
+ n_layers_D: 3
+ name: rhino_pix2pix_roi [default: experiment_name]
+ ndf: 64
+ netD: basic
+ netG: unet_256
+ ngf: 64
+ no_dropout: False
+ no_flip: False
+ norm: batch
+ num_test: -1 [default: 50]
+ num_threads: 4
+ output_nc: 3
+ phase: test
+ preprocess: none [default: resize_and_crop]
+ results_dir: results/ep100 [default: ./results/]
+ serial_batches: False
+ suffix:
+ use_wandb: False
+ verbose: False
+ wandb_project_name: CycleGAN-and-pix2pix
+----------------- End -------------------
+Traceback (most recent call last):
+ File "test.py", line 54, in
+ dataset = create_dataset(opt) # create a dataset given opt.dataset_mode and other options
+ File "/data1/liutao/pix2pix/data/__init__.py", line 60, in create_dataset
+ data_loader = CustomDatasetDataLoader(opt)
+ File "/data1/liutao/pix2pix/data/__init__.py", line 76, in __init__
+ self.dataset = dataset_class(opt)
+ File "/data1/liutao/pix2pix/data/aligned_dataset.py", line 16, in __init__
+ self.AB_paths = sorted(make_dataset(self.dir_AB, opt.max_dataset_size))
+ File "/data1/liutao/pix2pix/data/image_folder.py", line 36, in make_dataset
+ assert dir_path.is_dir(), f"{dir} is not a valid directory"
+AssertionError: datasets/rhino_aligned/test is not a valid directory
+Traceback (most recent call last):
+ File "tools/evaluate.py", line 7, in