diff --git a/.dockerignore b/.dockerignore
new file mode 100644
index 0000000000000000000000000000000000000000..c79212cabbf3ba7218f8984ca8af664088dc999b
--- /dev/null
+++ b/.dockerignore
@@ -0,0 +1,71 @@
+# =============================================================================
+# .dockerignore — keep the build context tiny.
+# Everything not needed by the backend runtime is excluded.
+# =============================================================================
+
+# --- VCS / IDE ---------------------------------------------------------------
+.git
+.github
+.gitignore
+.gitattributes
+.vscode
+.idea
+*.swp
+
+# --- Python caches & build artefacts -----------------------------------------
+__pycache__
+*.py[cod]
+*$py.class
+*.egg-info
+.eggs
+build
+dist
+.pytest_cache
+.mypy_cache
+.ruff_cache
+.coverage
+.coverage.*
+htmlcov
+.tox
+
+# --- Virtual envs ------------------------------------------------------------
+.venv
+venv
+env
+
+# --- Frontend (deployed separately to Vercel) --------------------------------
+frontend
+node_modules
+
+# --- Tests, notebooks, docs --------------------------------------------------
+tests
+notebooks
+docs
+assets
+scripts
+
+# --- Local dev / secrets -----------------------------------------------------
+.env
+.env.*
+!.env.example
+*.local
+
+# --- OS junk -----------------------------------------------------------------
+.DS_Store
+Thumbs.db
+
+# --- Docker / CI configs (not needed inside the image) -----------------------
+Dockerfile
+.dockerignore
+.pre-commit-config.yaml
+Makefile
+CLAUDE.md
+
+# --- Lockfiles / dev-only deps -----------------------------------------------
+requirements-dev.txt
+requirements-eval.txt
+
+# --- Model artefacts: keep ONLY the production version -----------------------
+# (Add explicit exceptions here if you publish multiple versions.)
+models/**/*.tar
+models/**/*.zip
diff --git a/.gitattributes b/.gitattributes
new file mode 100644
index 0000000000000000000000000000000000000000..b6ea0db224e5bdcbe10ba59776aa90312b3c1c0b
--- /dev/null
+++ b/.gitattributes
@@ -0,0 +1,39 @@
+*.7z filter=lfs diff=lfs merge=lfs -text
+*.arrow filter=lfs diff=lfs merge=lfs -text
+*.bin filter=lfs diff=lfs merge=lfs -text
+*.bz2 filter=lfs diff=lfs merge=lfs -text
+*.ckpt filter=lfs diff=lfs merge=lfs -text
+*.ftz filter=lfs diff=lfs merge=lfs -text
+*.gz filter=lfs diff=lfs merge=lfs -text
+*.h5 filter=lfs diff=lfs merge=lfs -text
+*.joblib filter=lfs diff=lfs merge=lfs -text
+*.lfs.* filter=lfs diff=lfs merge=lfs -text
+*.mlmodel filter=lfs diff=lfs merge=lfs -text
+*.model filter=lfs diff=lfs merge=lfs -text
+*.msgpack filter=lfs diff=lfs merge=lfs -text
+*.npy filter=lfs diff=lfs merge=lfs -text
+*.npz filter=lfs diff=lfs merge=lfs -text
+*.onnx filter=lfs diff=lfs merge=lfs -text
+*.ot filter=lfs diff=lfs merge=lfs -text
+*.parquet filter=lfs diff=lfs merge=lfs -text
+*.pb filter=lfs diff=lfs merge=lfs -text
+*.pickle filter=lfs diff=lfs merge=lfs -text
+*.pkl filter=lfs diff=lfs merge=lfs -text
+*.pt filter=lfs diff=lfs merge=lfs -text
+*.pth filter=lfs diff=lfs merge=lfs -text
+*.rar filter=lfs diff=lfs merge=lfs -text
+*.safetensors filter=lfs diff=lfs merge=lfs -text
+saved_model/**/* filter=lfs diff=lfs merge=lfs -text
+*.tar.* filter=lfs diff=lfs merge=lfs -text
+*.tar filter=lfs diff=lfs merge=lfs -text
+*.tflite filter=lfs diff=lfs merge=lfs -text
+*.tgz filter=lfs diff=lfs merge=lfs -text
+*.wasm filter=lfs diff=lfs merge=lfs -text
+*.xz filter=lfs diff=lfs merge=lfs -text
+*.zip filter=lfs diff=lfs merge=lfs -text
+*.zst filter=lfs diff=lfs merge=lfs -text
+*tfevents* filter=lfs diff=lfs merge=lfs -text
+
+# Frozen IEEE notebook: always check out with LF so the SHA-256 freeze check
+# (make freeze-paper-notebook) matches .paper-notebook.sha256 on every OS.
+notebooks/01_ieee_inceptionv3_transformer.ipynb text eol=lf
diff --git a/Dockerfile b/Dockerfile
new file mode 100644
index 0000000000000000000000000000000000000000..a61ab0065e2113022abcf328ef12f802e1f31f38
--- /dev/null
+++ b/Dockerfile
@@ -0,0 +1,58 @@
+# syntax=docker/dockerfile:1.7
+# =============================================================================
+# Dockerfile — FastAPI inference backend for HuggingFace Spaces (Docker SDK).
+# -----------------------------------------------------------------------------
+# Target: HF Spaces, hardware = cpu-basic (2 vCPU / 16 GB RAM).
+# Port: 7860 (HF Spaces convention).
+# User: UID 1000 named "user" (HF Spaces requirement).
+# Workdir: /home/user/app (HF Spaces convention).
+# Worker: uvicorn single worker — keeps the TF model loaded once in RAM.
+# =============================================================================
+
+FROM python:3.11-slim-bookworm
+
+ENV PYTHONDONTWRITEBYTECODE=1 \
+ PYTHONUNBUFFERED=1 \
+ PIP_DISABLE_PIP_VERSION_CHECK=1 \
+ PIP_NO_CACHE_DIR=1 \
+ TF_CPP_MIN_LOG_LEVEL=2 \
+ HF_HOME=/home/user/.cache/huggingface
+
+# libgomp1 is required by tensorflow-cpu (OpenMP runtime).
+# curl is used by HEALTHCHECK.
+RUN apt-get update \
+ && apt-get install -y --no-install-recommends libgomp1 curl \
+ && rm -rf /var/lib/apt/lists/*
+
+# HF Spaces requires a non-root user with UID 1000 named "user".
+RUN useradd --create-home --uid 1000 user
+USER user
+ENV PATH="/home/user/.local/bin:${PATH}"
+WORKDIR /home/user/app
+
+# --- Dependency layer (cached across code changes) ---------------------------
+COPY --chown=user:user requirements.txt ./
+RUN pip install --user --no-cache-dir -r requirements.txt
+
+# --- Application source ------------------------------------------------------
+# Copy only what the runtime needs. Build context is pruned by .dockerignore.
+COPY --chown=user:user pyproject.toml README.md ./
+COPY --chown=user:user src/ ./src/
+COPY --chown=user:user backend/ ./backend/
+COPY --chown=user:user configs/ ./configs/
+COPY --chown=user:user models/ ./models/
+
+# Install the local captioning package without re-resolving deps.
+RUN pip install --user --no-cache-dir --no-deps -e .
+
+EXPOSE 7860
+
+HEALTHCHECK --interval=30s --timeout=10s --start-period=90s --retries=3 \
+ CMD curl --fail --silent http://127.0.0.1:7860/healthz || exit 1
+
+CMD ["uvicorn", "app.main:app", \
+ "--app-dir", "backend", \
+ "--host", "0.0.0.0", \
+ "--port", "7860", \
+ "--workers", "1", \
+ "--log-level", "info"]
diff --git a/README.md b/README.md
new file mode 100644
index 0000000000000000000000000000000000000000..2a543b784e42669afba499d67ebedacbcf69decd
--- /dev/null
+++ b/README.md
@@ -0,0 +1,391 @@
+---
+title: Image Captioning API
+emoji: 🖼️
+colorFrom: blue
+colorTo: indigo
+sdk: docker
+app_port: 7860
+pinned: false
+license: mit
+short_description: InceptionV3 + Transformer image captioning inference API
+---
+
+Caption Studio
+
+
+ Upload a photo and get an English caption. The InceptionV3 + Transformer model from an IEEE paper, rebuilt from a research notebook into a tested, deployed full-stack system.
+
+
+
+  +
 +
 +
 +
 +
 +
 +
 +
+
+
+ Live app ·
+ Demo video ·
+ API docs ·
+ Architecture ·
+ Evaluation methodology ·
+ Paper
+
+
+## 🎬 Product Demo
+
+A short technical demo of the Image Captioning System's live image captioning, model inference pipeline and research-to-production checks.
+
+
+https://github.com/user-attachments/assets/7d63c76a-019f-4616-a219-fa4043f0233c
+
+
+**▶ [Watch the 27-second demo]** · [Try the live app](https://image-captioning-system.vercel.app) · [How the demo was made](docs/demo/README.md)
+
+**No photo to hand?** Under **Try an example**, the live app offers five licensed COCO images (CC BY 2.0, credited in the app) that go through the same validation and API call as an upload. Pick **Greedy** or **Beam search** before captioning, or press **Compare both** to run the two decoders on the same image one after the other, each with its measured latency. A **Dataset reference** card shows the caption a person wrote for that image in COCO.
+
+---
+
+Caption Studio describes an image in one sentence. A frozen InceptionV3 network turns the photo into a grid of visual features, and a Transformer decoder writes the caption word by word, either greedily or with beam search. The architecture comes from the IEEE paper *AI Narratives: Bridging Visual Content and Linguistic Expression* and its research notebook, which this repository keeps frozen. Around it sits what it takes for other people to use and maintain that model: an installable Python package, a FastAPI service on Hugging Face Spaces, a React app on Vercel, and CI that gates every deploy.
+
+The part worth reading first is the evaluation. With beam search, the deployed checkpoint scored BLEU-4 10.4 against the paper's ~24, and the obvious move was to retrain. A pre-registered, blinded audit showed the gap came mostly from how many reference captions each image is scored against: rescored against all five COCO references, the same captions reach 25.9. The audit also found the real weakness, which is that captions are fluent but often generic. Both findings are [reported below](#what-the-evaluation-taught-me), next to a comparison with three modern captioning models that is caveated rather than ranked.
+
+## At a glance
+
+| | |
+|---|---|
+| **Product** | React 19 app on Vercel → FastAPI on a Hugging Face Space (Docker, CPU) → one TensorFlow model loaded at startup. Upload a photo or pick an example; choose greedy or beam search, or compare both |
+| **Model** | Frozen InceptionV3 (ImageNet) → 1-layer Transformer encoder → 1-layer, 8-head Transformer decoder, 15,000-token vocabulary, trained on a 120,000-caption COCO 2017 sample. Served as `v2.0.0` from a commit-pinned, SHA-256-verified Hugging Face Hub revision |
+| **Caption quality** | CIDEr **0.789** greedy / **0.826** beam on 500 held-out COCO images with ~1.46 references each. BLEU-4 **25.9** when the beam captions are rescored against all 5 COCO references. A blinded review found 3 of 30 captions image-specific and correct |
+| **Live latency** | About 0.8–1.0 s (greedy) and 1.4–1.5 s (beam) of model inference per caption on the Space's CPU, about 3 s end to end including the upload. A handful of live requests, not a load test |
+| **Software checks** | 563 pytest tests and 27 Playwright browser tests, plus ruff, mypy, a 4-stage notebook parity audit, a SHA-256 notebook freeze, and dependency and secret scans. All of them block CI |
+| **Delivery** | A green push to `main` rebuilds the Space only if the image changed. A deploy passes only after the health check and one real caption from the live model |
+
+**Contents:** [What I built](#what-i-built) · [Architecture](#architecture) · [Evaluation](#evaluation) · [Engineering highlights](#engineering-highlights) · [Limitations](#limitations) · [Tech stack](#tech-stack) · [Run locally](#run-locally) · [Testing and CI](#testing-and-ci) · [Repository layout](#repository-layout) · [Roadmap](#roadmap) · [Documentation](#documentation) · [Publication](#publication-and-acknowledgements)
+
+---
+
+## What I built
+
+The paper defined the architecture and its notebook trained the original model. The rest was built in this repository:
+
+- **A web app** ([`frontend/`](frontend/)). React 19, Vite 8 and Tailwind v4: drag-and-drop upload with client-side type and size checks, the example gallery, the Greedy / Beam search / Compare both controls, a live API health badge, and a static **Phase 3 comparison** view of the baseline results.
+- **An inference API** ([`backend/app/`](backend/app/)). FastAPI with a Pydantic schema for every request and response, one warm model per process, TensorFlow work moved off the event loop, bounded admission, and a status-code contract shared with the frontend.
+- **A modular ML package** ([`src/captioning/`](src/captioning/)). The notebook split into config, preprocessing, data, models, training, greedy and beam-search inference, and evaluation, with a parity audit that proves the split didn't change behaviour.
+- **A retrained checkpoint.** The stabilized recipe (label smoothing, warmup into cosine decay), trained on COCO 2017 on Kaggle and published to the Hub as `v2.0.0`. This is what the live app serves.
+- **Evaluation tooling.** BLEU-1–4, METEOR, ROUGE-L and CIDEr on a fixed slice, one machine-readable artefact set per run, and a harness that compares the model with BLIP, ViT-GPT2 and GIT under a protocol committed before any result.
+- **Delivery.** A Docker image on Hugging Face Spaces, Vercel for the frontend, and GitHub Actions for CI, security scanning and gated deploys.
+
+## Architecture
+
+```mermaid
+flowchart TB
+ subgraph live["Serving path (live)"]
+ SPA["React 19 SPA · Vercel
upload · example gallery
greedy / beam / compare both"]
+ API["FastAPI · Hugging Face Space
Docker, CPU, 1 worker
GET /healthz · POST /v1/captions"]
+ PRED["CaptionPredictor
one warm model · 2 inference slots"]
+ SPA -- "multipart image + decode_strategy" --> API --> PRED
+ end
+
+ subgraph offline["Research and evaluation"]
+ NB["IEEE notebook
frozen, SHA-256 locked"]
+ PKG["src/captioning
config · data · models · training
inference · evaluation"]
+ TRAIN["Training on Kaggle
configs/train/stabilized.yaml"]
+ RES[("results/<run_id>/
metrics · predictions · audits")]
+ NB -- "4-stage parity audit in CI" --- PKG
+ PKG --> TRAIN
+ PKG -- "evaluate · compare · benchmark" --> RES
+ end
+
+ TRAIN -- "publish v2.0.0" --> HUB[("Hugging Face Hub
model.h5 · vocab.json")]
+ HUB -. "pinned commit, SHA-256 checked at startup" .-> PRED
+ RES -. "exported to JSON at build time" .-> SPA
+```
+
+The two halves meet in two places: the Hub weights the API downloads at startup, and the results JSON the SPA bundles at build time. The serving image contains no notebook, no training data and no evaluation results. The notebook is the published research artefact and stays byte-for-byte as it was; every improvement goes into the package, behind the parity audit.
+
+### Inference pipeline
+
+```text
+POST /v1/captions multipart: image, optional decode_strategy
+ → body cap 413 before a body over 10 MiB (+64 KiB framing) is buffered
+ → decode_strategy greedy (default) or beam, otherwise 422
+ → content-type allow-list JPEG · PNG · BMP, otherwise 415 (WebP and GIF included)
+ → bounded read 400 if empty, 413 if over 10 MiB
+ → admission 503 + Retry-After: 2 while both inference slots are busy
+ → header check + decode 413 over 16,384 px a side or 40 MP, before TensorFlow decodes; 422 if undecodable
+ → preprocess_image_tensor 299×299, InceptionV3 scaling: the same function training uses
+ → InceptionV3 (frozen) 8×8×2048 feature map → 64 image tokens
+ → Transformer encoder 1 layer, 1 head, 512-dim
+ → Transformer decoder 1 layer, 8 heads; greedy, or beam search (width 4)
+ → CaptionResponse caption · model_version · decode_strategy · latency_ms · request_id
+```
+
+Beam search runs with exactly the settings of the evaluated beam run: width 4, length penalty 0.7, repetition penalty 1.2, no repeated trigrams. A live beam caption is therefore the decoder the metrics below describe.
+
+| Endpoint | Behaviour |
+|---|---|
+| [`GET /healthz`](https://apoorvrajdev-image-captioning-api.hf.space/healthz) | Always 200; `model_loaded` and `model_version` report readiness. Runs on the event loop, so it never waits behind inference |
+| `POST /v1/captions` | Image in, `CaptionResponse` out. Status codes 200 / 400 / 413 / 415 / 422 / 503, each covered by a backend test and consumed by [`frontend/src/services/api.js`](frontend/src/services/api.js) |
+| [`GET /docs`](https://apoorvrajdev-image-captioning-api.hf.space/docs) | Swagger UI generated from the Pydantic schemas |
+
+**Where it runs.** The SPA is on [Vercel](https://image-captioning-system.vercel.app), rebuilt on every push to `main`. The API is a [Hugging Face Space](https://huggingface.co/spaces/apoorvrajdev/image-captioning-api): Docker, `python:3.11-slim`, a non-root user, one uvicorn worker on a CPU instance. The weights are in the Hub repo [`apoorvrajdev/captioning-inceptionv3-transformer`](https://huggingface.co/apoorvrajdev/captioning-inceptionv3-transformer) at tag `v2.0.0`, which the backend resolves to commit `59d93b4`. Topology, promotion and rollback are in the [deployment runbook](docs/PHASE_2C_DEPLOYMENT_RUNBOOK.md).
+
+## Evaluation
+
+Every number in this section comes from a committed run directory under [`results/`](results/). The evaluation slice is 500 COCO 2017 `train2017` images from the model's own image-level validation split, so the model never trained on them. They are scored against the 732 reference captions stored with them, about 1.46 per image. That is fewer than the standard five per image, which lowers BLEU in particular; [the audit below](#what-the-evaluation-taught-me) measures by how much.
+
+### Caption quality
+
+| Decoding | BLEU-1 | BLEU-4 | METEOR | ROUGE-L | CIDEr |
+|---|---|---|---|---|---|
+| Greedy ([run](results/stabilized-greedy/)) | 42.20 | 10.57 | 15.45 | 37.57 | 0.789 |
+| Beam search, width 4 ([run](results/stabilized-beam-w4-lp07-rp12/)) | 41.93 | 10.39 | 15.56 | 36.84 | **0.826** |
+
+Beam search gives slightly less n-gram overlap but about 5% more CIDEr, the metric that rewards image-specific wording over generic phrases. That is why the app lets you choose. BLEU-2 and BLEU-3, predictions and per-sample diagnostics are in each run directory.
+
+The served checkpoint used the stabilized recipe ([`configs/train/stabilized.yaml`](configs/train/stabilized.yaml)): the notebook's architecture and hyperparameters, plus label smoothing 0.1, a 500-step warmup into cosine decay, and dropout off during validation. It trained on 120,000 COCO 2017 captions, split 80/20 by image, for 10 epochs at batch 64. Training loss fell from 4.69 to 3.33, and validation accuracy rose every epoch, from 0.429 to 0.475 ([`history.json`](results/history.json)).
+
+### Sample captions
+
+These are the five example images in the live app, with the served `v2.0.0` checkpoint's captions from the committed evaluation runs. The kitten captions are the ones the deployed app returned in the [demo recording](docs/demo/README.md).
+
+| Image | Greedy | Beam search | COCO reference (written by a person) |
+|---|---|---|---|
+| 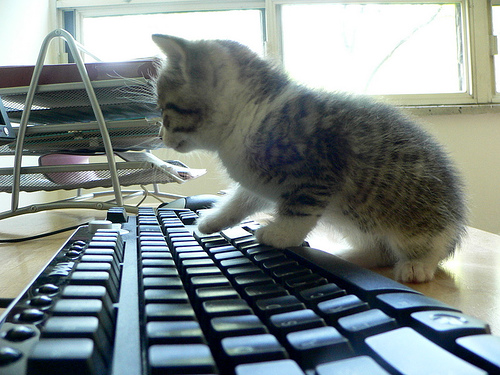 | a cat is sitting on a keyboard of a computer | a close up of a cat laying on a keyboard | A kitten sitting on the keyboard of a computer. |
+|
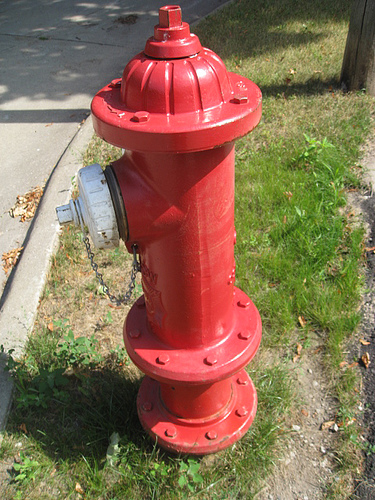 | a red fire hydrant sitting on a sidewalk | a red fire hydrant sitting on the side of a road | A red fire hydrant sitting on the side of a road. |
+|
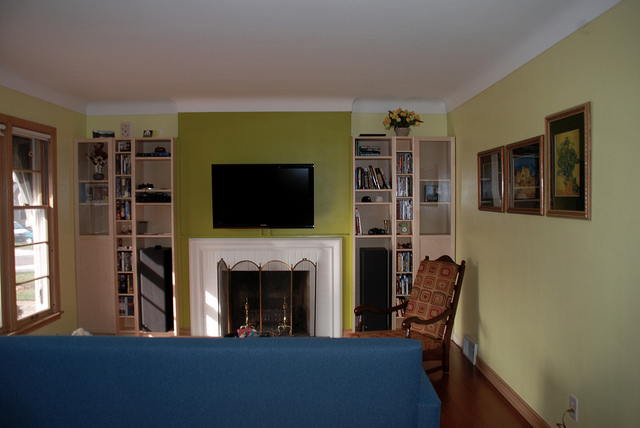 | a living room with a couch and a tv | a living room filled with furniture and a flat screen tv | a small living room with a blue couch, flat screen television and a fireplace |
+|
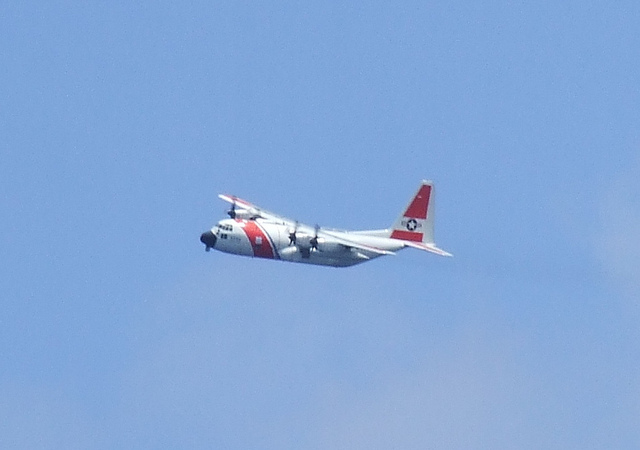 | a large airplane flying through the sky | an airplane is flying in the sky on a cloudy day | An airplane flying through a blue sky with propellers. |
+|
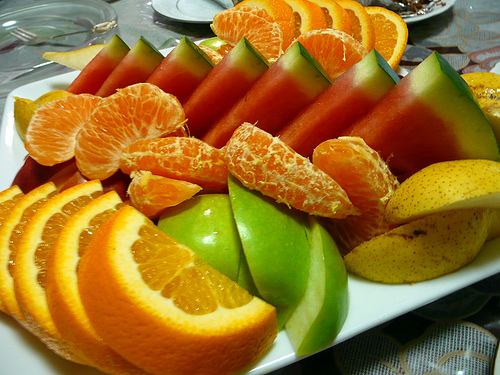 | a plate of fruit and a salad with a fork | a close up of a plate of food on a table | A collection of fruits are stacked on a plate. |
+
+Neither decoder wins every image. Beam search matches the reference wording on the hydrant and adds the flat-screen TV in the living room, but it calls a clear blue sky cloudy and is vaguer than greedy on the fruit platter.
+
+Images: COCO 2017 via Flickr, CC BY 2.0: “Mango HaX0ring” by Slava · “07252008” by pa1nt · “Living room w/painted cable covers” by Amy West · “US Coast Guard Herc” by Simon_sees · “fruit platter” by >littleyiye<. Reference captions: COCO Consortium, CC BY 4.0.
+
+### What the evaluation taught me
+
+**Before retraining a model to close a gap, check whether the gap is real.**
+
+The beam checkpoint's BLEU-4 of 10.39 looked about 14 points behind the ~24 the paper reports. Instead of spending GPU hours on a retrain, I ran a pre-registered, blinded audit ([`EVAL_METHODOLOGY.md`](docs/EVAL_METHODOLOGY.md) §§ 1–7). The hypotheses and decision thresholds were committed before any result, and the qualitative review was judged before the BLEU result was unblinded.
+
+| The same 500 beam captions, scored against | References per image | BLEU-4 |
+|---|---|---|
+| The references stored with the slice | ~1.46 | 10.39 |
+| All COCO references for those images | 5 | **25.91** |
+
+BLEU credits an n-gram that matches *any* reference, so the reference count alone moved the headline number by 15 points. Scored on the paper's footing, the checkpoint lands in the same range as the paper. That is **methodology parity, not a claim of beating the paper**. The audit also measured a smaller effect from BLEU smoothing and aggregation: NLTK's variants score the same captions 22.2–23.8 ([`metrics_5ref.json`](results/stabilized-beam-w4-lp07-rp12/metrics_5ref.json)).
+
+The blinded review of 30 beam captions found the real weakness:
+
+| Category | Captions |
+|---|---|
+| Specific and correct: the right subject plus a distinguishing detail | 3 |
+| Correct but generic ("a person on a beach") | 11 |
+| Partly correct: a count, colour, action or secondary object wrong | 15 |
+| Incorrect | 1 |
+
+Captions are fluent and usually on topic, but mostly generic. With 30 samples, each proportion is uncertain by up to about ±18 percentage points. The verdict was **reframe, do not retrain** ([`verdict.md`](results/stabilized-beam-w4-lp07-rp12/verdict.md)): the BLEU gap was mostly the evaluation setup, and specificity is limited by the frozen ImageNet encoder, which the original training recipe would not change. Retraining on the paper's recipe stays on the [roadmap](#roadmap) as an experiment, not a fix.
+
+### Comparison with BLIP, ViT-GPT2 and GIT
+
+Phase 3 scored three Hugging Face captioning models on the same 500 images and references, at pinned revisions with greedy decoding. The protocol was committed before the first baseline ran ([`EVAL_METHODOLOGY.md`](docs/EVAL_METHODOLOGY.md) § 8).
+
+> **Read this table as context, not a ranking.** The slice is held out for this repository's model only. BLIP's and GIT's model cards state COCO training, and ViT-GPT2 may have used it, so the baselines may have seen these exact images; per-image overlap isn't measured (§ 8.5). With ~1.46 references per image, none of these scores is comparable with published COCO results either.
+
+| Model | Decoding | BLEU-4 | METEOR | ROUGE-L | CIDEr |
+|---|---|---|---|---|---|
+| BLIP-base | greedy | 19.88 | 17.23 | 42.13 | 1.06 |
+| GIT-base-coco | greedy | 18.83 | 21.92 | 47.08 | 1.46 |
+| CNN + Transformer (this repo) | beam | 10.39 | 15.56 | 36.84 | 0.83 |
+| CNN + Transformer (this repo) | greedy | 10.57 | 15.45 | 37.57 | 0.79 |
+| ViT-GPT2 | greedy | 15.84 | 19.78 | 44.51 | 1.26 |
+
+Rows follow [`comparison.md`](results/phase3-comparison/comparison.md), ordered by model id. All three baselines score higher on this slice. Because they may have trained on these images, the table can't say how large that gap is on genuinely unseen images. What it does establish is that the harness reproduces this repository's own results exactly: re-running the greedy row through it gave 500/500 identical captions and bit-identical metrics (§ 8.8).
+
+Latency for all four models, on CPU (a local laptop) and on a Kaggle T4 GPU, is in §§ 9.9–9.10 and in the app's **Phase 3 comparison** view. The two devices were different hosts, so the figures compare models within a device, not CPU against GPU. This model's batch-8 figure is eight sequential calls rather than one batched call.
+
+## Engineering highlights
+
+- **The notebook is frozen, and parity is tested, not assumed.** The paper's notebook stays byte-for-byte as published, locked by a SHA-256 check in CI. A four-stage audit ([`scripts/notebook_module_audit.py`](scripts/notebook_module_audit.py)) re-implements caption preprocessing, tokenisation, image preprocessing and the decoder forward pass from the notebook, and asserts the package matches them. Every later improvement is opt-in behind a flag whose default reproduces the notebook, so a changed number always traces back to one named change.
+- **Training and serving share one preprocessing path.** Uploads go through the same `preprocess_image_tensor` that builds the training pipeline, so the model never sees pixels normalised differently in production than in training.
+- **Uploads are bounded before they cost anything.** A middleware refuses oversized bodies before the multipart parser buffers them, and the route reads at most one byte past the limit. A header check rejects images over 16,384 px a side or 40 megapixels before TensorFlow decodes them. WebP is refused at the door because TensorFlow 2.15 can't decode it, instead of failing deep inside the model.
+- **Inference is bounded too.** The Space runs one CPU worker. At most two captions decode at once, and the next request gets an immediate 503 with `Retry-After: 2` rather than joining a queue that slows everyone down. `/healthz` runs on the event loop, so a busy model never fails the health check.
+- **The weights are pinned and verified.** Hub tags can be moved, so the backend resolves `v2.0.0` to a commit id written in reviewed code. It downloads only `model.h5` and `vocab.json` and checks both against SHA-256 digests pinned per commit before anything reads them. The vocabulary loads from validated JSON instead of unpickling a file from the network ([ADR-032, ADR-033](docs/DECISIONS.md)).
+- **Decoding is a per-request choice on one model.** Greedy is the default, and beam search uses the evaluated settings. Compare both in the app is two ordinary requests to the same loaded weights, not a second model.
+- **Configuration is strict.** Every config model is Pydantic v2 with `extra="forbid"`, so a misspelt hyperparameter fails at load instead of silently falling back to a default. Research settings (`CAPTIONING__*`) and deployment settings (`BACKEND_*`) are separate objects, and environment variables outrank the YAML ([ADR-029](docs/DECISIONS.md)).
+- **Only tested commits deploy, and only when needed.** After green CI, the Space rebuilds only if an image input changed since the last successful deploy, and it receives a single-commit snapshot of exactly the tested build context. A deploy passes only once the health check reports the model loaded and one real caption comes back from the live Space ([ADR-027, ADR-028, ADR-030](docs/DECISIONS.md)).
+- **Results are artefacts, not prose.** Every evaluation writes a run directory with metrics, predictions and per-sample diagnostics, and run directories are never rewritten. The app's comparison view is exported from those files at build time, and a test fails if the two disagree ([ADR-021](docs/DECISIONS.md)).
+- **TensorFlow is pinned at 2.15 on purpose.** TensorFlow 2.16 switches to Keras 3, which breaks `TextVectorization` save and load, and serving depends on that tokenizer round trip. The baselines' `torch` and `transformers` live in an optional `[hf]` extra and are imported lazily, so the serving image never installs them.
+
+## Limitations
+
+### Model
+
+- Captions are often generic, and count, colour and attribute mistakes are common (see the blinded review above, and [`qualitative.jsonl`](results/stabilized-beam-w4-lp07-rp12/qualitative.jsonl) for 30 predictions next to their references). This is a frozen ImageNet CNN with a one-layer decoder, trained for 10 epochs on a 120,000-caption sample: a working demonstration of the paper's model, not a general-purpose captioner.
+- It writes English only, in the vocabulary of COCO's everyday scenes. Unusual compositions fall back to generic captions.
+- Quality is measured on one 500-image slice with ~1.46 references per image. The 5-reference rescore covers BLEU only.
+- The baseline comparison is not held out for the baselines, as explained above.
+
+### System
+
+- It is a public demo with no authentication and no rate limiting. One heavy client can keep both inference slots busy, and everyone else gets the 503 until a slot frees.
+- It runs on a CPU and one worker. The first request after an idle period can be slow while the Space wakes up.
+- The Hugging Face proxy answers CORS itself and reflects any origin, so the app's allowed-origin list isn't enforced at the edge.
+- The frontend has no unit tests. The browser tests run on Chromium only, against a mocked API.
+
+The full list, with risks and suggested fixes, is in [`SECURITY.md`](docs/SECURITY.md) § Known gaps and [`PHASE_1_NOTES.md`](docs/PHASE_1_NOTES.md#technical-debt-remaining).
+
+## Tech stack
+
+| Area | Technologies |
+|---|---|
+| **Frontend** | React 19, Vite 8, Tailwind CSS v4, ESLint (flat config) |
+| **Backend** | FastAPI 0.133, Starlette 1.3, Pydantic v2 and pydantic-settings, Uvicorn, structlog, anyio |
+| **ML and inference** | TensorFlow-CPU 2.15 (pinned), NumPy 1.26, Pillow, `huggingface-hub` |
+| **Evaluation** | sacrebleu (BLEU), pycocoevalcap (CIDEr, METEOR), rouge-score (ROUGE-L); optional `[hf]` extra with `torch` 2.3.0 and `transformers` 4.41.2 for the baselines |
+| **Testing and quality** | pytest, Playwright (Chromium), ruff, mypy, pre-commit (including nbstripout and gitleaks), pip-audit, npm audit |
+| **Deployment** | Docker, Hugging Face Spaces and Hub, Vercel, GitHub Actions |
+
+## Run locally
+
+**Prerequisites:** Python 3.10–3.12 (TensorFlow 2.15 has no 3.13 wheels), Node 20.19+ or 22.12+ (the range Vite 8 supports), and Git.
+
+```bash
+# Backend: install (on Windows, activate with .venv\Scripts\activate)
+python3.10 -m venv .venv && source .venv/bin/activate
+pip install -r requirements-dev.txt -r requirements-eval.txt
+pip install -e ".[hf,mlflow]"
+
+# Serve the published v2.0.0 weights: downloaded from the Hub on first start, SHA-256-checked before loading
+export BACKEND_WEIGHTS_HUB_REPO=apoorvrajdev/captioning-inceptionv3-transformer
+export BACKEND_WEIGHTS_HUB_REVISION=v2.0.0
+export BACKEND_MODEL_VERSION=v2.0.0
+uvicorn app.main:app --app-dir backend --port 8000 # Swagger UI at http://localhost:8000/docs
+
+# Frontend, in a second terminal
+cd frontend
+npm install
+npm run dev # http://localhost:5173
+```
+
+The SPA calls `http://127.0.0.1:8000` unless `VITE_API_BASE` is set (see [`frontend/.env.example`](frontend/.env.example)). To caption from the command line:
+
+```bash
+curl -F "image=@photo.jpg" -F "decode_strategy=beam" http://localhost:8000/v1/captions
+```
+
+Without network access, [`scripts/bootstrap_dev_artifacts.py`](scripts/bootstrap_dev_artifacts.py) writes untrained weights that boot the whole stack; their captions are gibberish by design. Training needs COCO 2017 locally: `python -m scripts.train --config configs/train/stabilized.yaml --output-dir outputs/runs/stabilized`, with the full procedure in the [stabilized training runbook](docs/STABILIZED_TRAINING_RUNBOOK.md). Deployment, weights promotion and rollback are in the [deployment runbook](docs/PHASE_2C_DEPLOYMENT_RUNBOOK.md).
+
+## Testing and CI
+
+| Suite | Command | Tests |
+|---|---|---|
+| Library and script unit tests | `pytest tests -q` | 446 |
+| Backend route tests (fake predictor, no TensorFlow) | `pytest backend/app/tests -q` | 117 |
+| Browser E2E (Playwright, Chromium, API mocked) | `cd frontend && npm run test:e2e` | 27 |
+| Notebook parity audit | `python -m scripts.notebook_module_audit` | 4 stages |
+
+Every test is CPU-only and offline: no network, no model download. Playwright needs `npx playwright install chromium` once per machine. The exact lint and type-check invocations are in [`docs/CI.md`](docs/CI.md) § Local equivalents.
+
+CI ([`ci.yml`](.github/workflows/ci.yml)) runs on every push and pull request to `main`, and every job blocks:
+
+| Job | Checks |
+|---|---|
+| Python quality | ruff lint and format check, mypy |
+| pytest (Python 3.10 and 3.11) | all 563 tests, then the parity audit |
+| Notebook freeze | the notebook's SHA-256 against `.paper-notebook.sha256` |
+| pre-commit | every hook on every file |
+| Security | pip-audit of `requirements.txt` against a reviewed baseline, gitleaks over the full history |
+| Frontend | ESLint, production build, Playwright E2E, `npm audit --omit=dev` |
+
+After a green run on `main`, [`deploy-backend.yml`](.github/workflows/deploy-backend.yml) decides whether the Space image changed, deploys the tested commit if it did, and gates on the health check and a real caption. Vercel deploys the frontend through its Git integration.
+
+## Repository layout
+
+```text
+image-captioning-system/
+├── notebooks/ # the paper's notebook, frozen (hash in .paper-notebook.sha256)
+├── src/captioning/ # installable package
+│ ├── config/ # Pydantic v2 schema, YAML + environment loader
+│ ├── preprocessing/ # caption cleanup, image preprocessing shared by training and serving, tokenizer
+│ ├── data/ # COCO loading, image-level split, tf.data pipeline
+│ ├── models/ # InceptionV3 encoder, Transformer encoder and decoder, model factory
+│ ├── training/ # losses, learning-rate schedule, trainer
+│ ├── inference/ # CaptionPredictor, greedy and beam-search decoders
+│ ├── evaluation/ # metrics, run artefacts, Phase 3 comparison and latency
+│ └── baselines/ # one Captioner interface for this model and the Hugging Face baselines
+├── backend/app/ # FastAPI: routes, schemas, services (predictor, weights loader), settings, tests
+├── frontend/ # React SPA; src/services/api.js is the only API boundary, e2e/ the Playwright suite
+├── configs/ # base.yaml reproduces the notebook; train/stabilized.yaml is the served recipe
+├── scripts/ # train, evaluate, predict, compare, benchmark, parity audit, deploy helpers
+├── results/ # committed evaluation runs, append-only
+├── tests/unit/ # library and script tests
+├── docs/ # methodology, runbooks, decisions, security, task history
+├── Dockerfile # the Hugging Face Space image
+└── .github/workflows/ # CI and the gated Space deploy
+```
+
+## Roadmap
+
+Phases 0–4 are complete: modularisation behind a parity gate, training stabilisation and the metric suite, the API and web app, public deployment, the baseline comparison, and production hardening. Work since then has hardened the upload path and the weights supply chain and added the example gallery and per-request decoding.
+
+
+Completed phases
+
+- **Phase 0, bootstrap.** Packaging, pre-commit hooks, the notebook freeze and pinned dependencies.
+- **Phase 1, modularisation.** The notebook split into the `captioning` package behind the four-stage parity audit, with strict typed configuration and unit tests.
+- **Phase 1b, training stabilisation.** Beam search, the BLEU / METEOR / ROUGE-L / CIDEr suite with per-run artefacts, the opt-in stabilized recipe and the `v2.0.0` checkpoint, then the Stage 0 evaluation audit (reframe, do not retrain).
+- **Phase 2, serving and deployment.** The FastAPI service (2A), the React SPA (2B), and public deployment on Hugging Face Spaces and Vercel with CI/CD (2C).
+- **Phase 3, multimodal baselines.** The pre-registered comparison with BLIP, ViT-GPT2 and GIT, CPU and GPU latency, the static comparison view, and Playwright E2E.
+- **Phase 4, production hardening.** A pinned CI platform, upgraded serving dependencies, dependency and secret scanning, deploys only when the image changes, and the post-deploy caption check.
+- **Since Phase 4.** Environment variables that outrank the YAML, single-commit Space snapshots, pre-decode pixel limits, bounded inference admission, commit-pinned and SHA-256-verified weights, the example gallery, and per-request greedy or beam decoding with Compare both.
+
+Task-by-task history, with the verification behind each task: [`docs/TASKS.md`](docs/TASKS.md).
+
+
+
+**Possible next steps.** These are directions, not current capabilities:
+
+- **Original-recipe ablation.** Retrain with the paper's recipe (constant Adam, no label smoothing, early stopping) under the same evaluation, to find out whether it beats the stabilized recipe on this architecture.
+- **A stronger encoder.** Specificity is limited by the frozen InceptionV3. Fine-tuning a modern vision-language captioner such as BLIP-2 on COCO, under the same protocol, would show what better captions cost per request.
+- **Streaming captions.** Server-sent events from `/v1/captions`, so the app shows words as the decoder produces them.
+- **Batch captioning.** One request for a list of images, to amortise per-request overhead.
+- **Visual question answering.** A `POST /v1/vqa` route that reuses the warm encoder.
+- **Online evaluation.** Score each new checkpoint on a held-out slice automatically and publish quality and latency over time.
+
+## Documentation
+
+| Document | What it covers |
+|---|---|
+| [`docs/EVAL_METHODOLOGY.md`](docs/EVAL_METHODOLOGY.md) | The Stage 0 audit (§§ 1–7), the Phase 3 comparison protocol and results (§ 8), and the latency protocol and results (§ 9) |
+| [`docs/PHASE_2C_DEPLOYMENT_RUNBOOK.md`](docs/PHASE_2C_DEPLOYMENT_RUNBOOK.md) | Deployment topology, Space and Vercel setup, weights promotion and rollback |
+| [`docs/CI.md`](docs/CI.md) | Every CI and deploy job, and their local equivalents |
+| [`docs/SECURITY.md`](docs/SECURITY.md) | Controls in place, known gaps, the dependency audit and the CI scanning policy |
+| [`docs/DECISIONS.md`](docs/DECISIONS.md) | Architecture decision records |
+| [`docs/TEST_PLAN.md`](docs/TEST_PLAN.md) | The checks each kind of change must pass |
+| [`docs/STABILIZED_TRAINING_RUNBOOK.md`](docs/STABILIZED_TRAINING_RUNBOOK.md) | How the stabilized checkpoint was trained |
+| [`docs/TASKS.md`](docs/TASKS.md) · [`docs/MEMORY.md`](docs/MEMORY.md) | Task history with verification records · current project state |
+| [`notebooks/README.md`](notebooks/README.md) | The frozen-notebook policy |
+| [`docs/demo/README.md`](docs/demo/README.md) | How the demo video was made, what in it is real, and its credits |
+| [`docs/PHASE_0_NOTES.md`](docs/PHASE_0_NOTES.md) · [`docs/PHASE_1_NOTES.md`](docs/PHASE_1_NOTES.md) · [`docs/restructure-plan.md`](docs/restructure-plan.md) | Early phase notes and the original restructure plan |
+
+## Publication and acknowledgements
+
+The model architecture and the original notebook come from:
+
+> Preetam, S. C. Muppalla, A. Raj and J. Chawla, "AI Narratives: Bridging Visual Content and Linguistic Expression," *2024 IEEE International Conference on Smart Power Control and Renewable Energy (ICSPCRE)*, 2024. doi: [10.1109/ICSPCRE62303.2024.10675203](https://doi.org/10.1109/ICSPCRE62303.2024.10675203) · [IEEE Xplore](https://ieeexplore.ieee.org/document/10675203)
+
+The notebook is kept verbatim at [`notebooks/01_ieee_inceptionv3_transformer.ipynb`](notebooks/01_ieee_inceptionv3_transformer.ipynb). Improvements go into `src/captioning/`, never into the notebook.
+
+- **[COCO 2017](https://cocodataset.org/)** provides the training and evaluation data. The annotations are CC BY 4.0, and each image keeps its own Flickr licence.
+- **InceptionV3** ImageNet weights come from Keras Applications.
+- **BLIP-base** (Salesforce), **ViT-GPT2** (nlpconnect) and **GIT-base-coco** (Microsoft), from the Hugging Face Hub, are used for evaluation only and are never served.
+- The demo video's music, sound effects and typefaces are credited in [`docs/demo/README.md`](docs/demo/README.md#credits).
+
+## License
+
+Released under the [MIT License](LICENSE). Built by [apoorvrajdev](https://github.com/apoorvrajdev) · [apoorvrajmgr@gmail.com](mailto:apoorvrajmgr@gmail.com)
diff --git a/backend/app/__init__.py b/backend/app/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..99ff3903922bc0a6777f000814dbb36db2a7a563
--- /dev/null
+++ b/backend/app/__init__.py
@@ -0,0 +1 @@
+"""FastAPI inference backend for the captioning ML package."""
diff --git a/backend/app/api/__init__.py b/backend/app/api/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..3722a03767c96c11ba8d3831dbb4d453bf2299bc
--- /dev/null
+++ b/backend/app/api/__init__.py
@@ -0,0 +1,5 @@
+"""HTTP routes for the captioning service."""
+
+from app.api.routes import router
+
+__all__ = ["router"]
diff --git a/backend/app/api/routes.py b/backend/app/api/routes.py
new file mode 100644
index 0000000000000000000000000000000000000000..8de0843e38b5eff0a3773831911e60f6e02a901c
--- /dev/null
+++ b/backend/app/api/routes.py
@@ -0,0 +1,170 @@
+"""HTTP routes: ``/healthz`` and ``/v1/captions``.
+
+Routes are intentionally thin: validate inputs, delegate to the
+``PredictorService``, shape the response. No model code, no TF imports.
+"""
+
+from __future__ import annotations
+
+from datetime import datetime, timezone
+
+from fastapi import APIRouter, Depends, File, Form, HTTPException, Request, UploadFile, status
+
+from app.core.config import BackendSettings
+from app.core.logging import current_request_id
+from app.schemas.caption import CaptionResponse, ErrorResponse, HealthResponse
+from app.services.predictor_service import (
+ DECODE_STRATEGIES,
+ PredictorBusyError,
+ PredictorService,
+)
+from app.utils.image import ALLOWED_CONTENT_TYPES, ImageDecodeError, ImageTooLargeError
+from captioning.utils import get_logger
+
+log = get_logger(__name__)
+
+router = APIRouter()
+
+# The overload 503. One caption took 0.8-0.9 s of inference in the deploy smoke
+# tests, so a slot usually frees within a couple of seconds.
+BUSY_DETAIL = "The server is busy with other captions. Retry in a few seconds."
+BUSY_RETRY_AFTER_SECONDS = 2
+
+
+async def get_predictor_service(request: Request) -> PredictorService:
+ """Resolve the singleton ``PredictorService`` from app state.
+
+ Returns 503 instead of crashing if the lifespan hasn't finished loading
+ weights yet (which can happen if ``/v1/captions`` is hit during a
+ rolling restart). Async, so FastAPI resolves it on the event loop rather
+ than in a worker thread that busy inference might be holding.
+ """
+ service: PredictorService | None = getattr(request.app.state, "predictor_service", None)
+ if service is None:
+ raise HTTPException(
+ status_code=status.HTTP_503_SERVICE_UNAVAILABLE,
+ detail="Predictor is not ready yet.",
+ )
+ return service
+
+
+@router.get(
+ "/healthz",
+ response_model=HealthResponse,
+ tags=["health"],
+ summary="Liveness + readiness probe",
+)
+async def healthz(request: Request) -> HealthResponse:
+ """Return readiness state. Always 200 — readiness is conveyed by ``model_loaded``.
+
+ Runs entirely on the event loop, with no sync dependency, so it never
+ waits for a worker thread that inference might be holding.
+ """
+ settings: BackendSettings = request.app.state.backend_settings
+ service: PredictorService | None = getattr(request.app.state, "predictor_service", None)
+ return HealthResponse(
+ status="ok" if service is not None else "loading",
+ model_loaded=service is not None,
+ model_version=service.model_version if service is not None else settings.model_version,
+ api_version=settings.api_version,
+ timestamp=datetime.now(timezone.utc),
+ )
+
+
+@router.post(
+ "/v1/captions",
+ response_model=CaptionResponse,
+ tags=["captions"],
+ status_code=status.HTTP_200_OK,
+ summary="Generate a caption for an uploaded image",
+ responses={
+ 400: {"model": ErrorResponse, "description": "Empty upload."},
+ 413: {
+ "model": ErrorResponse,
+ "description": "Image exceeds the upload size or pixel-dimension limit.",
+ },
+ 415: {"model": ErrorResponse, "description": "Unsupported image content type."},
+ 422: {
+ "model": ErrorResponse,
+ "description": "Image bytes could not be decoded, or `decode_strategy` is unknown.",
+ },
+ 503: {
+ "model": ErrorResponse,
+ "description": "Predictor not ready, or every inference slot is busy (with `Retry-After`).",
+ },
+ },
+)
+async def caption_image(
+ image: UploadFile = File(
+ ...,
+ description="Image file to caption. Allowed: JPEG, PNG, BMP.",
+ ),
+ decode_strategy: str | None = Form(
+ None,
+ description=(
+ "Decoding strategy for this request: `greedy` (the default) or `beam`. "
+ "Beam search uses the server's configured width and penalties."
+ ),
+ ),
+ service: PredictorService = Depends(get_predictor_service),
+) -> CaptionResponse:
+ """Accept a multipart image upload and return a generated caption."""
+ if decode_strategy is not None and decode_strategy not in DECODE_STRATEGIES:
+ raise HTTPException(
+ status_code=status.HTTP_422_UNPROCESSABLE_CONTENT,
+ detail=(
+ f"Unsupported decode_strategy: {decode_strategy!r}. "
+ f"Allowed: {list(DECODE_STRATEGIES)}."
+ ),
+ )
+ if image.content_type not in ALLOWED_CONTENT_TYPES:
+ raise HTTPException(
+ status_code=status.HTTP_415_UNSUPPORTED_MEDIA_TYPE,
+ detail=(
+ f"Unsupported content type: {image.content_type!r}. "
+ f"Allowed: {sorted(ALLOWED_CONTENT_TYPES)}."
+ ),
+ )
+
+ # Read at most one byte past the limit: enough to detect an oversized
+ # upload without pulling the whole file into memory.
+ payload = await image.read(service.max_upload_bytes + 1)
+ if not payload:
+ raise HTTPException(
+ status_code=status.HTTP_400_BAD_REQUEST,
+ detail="Empty file upload.",
+ )
+ if len(payload) > service.max_upload_bytes:
+ raise HTTPException(
+ status_code=status.HTTP_413_CONTENT_TOO_LARGE,
+ detail=f"Image exceeds the {service.max_upload_bytes}-byte upload limit.",
+ )
+
+ try:
+ caption, latency_ms = await service.caption_image_bytes(
+ payload, decode_strategy=decode_strategy
+ )
+ except PredictorBusyError as exc:
+ raise HTTPException(
+ status_code=status.HTTP_503_SERVICE_UNAVAILABLE,
+ detail=BUSY_DETAIL,
+ headers={"Retry-After": str(BUSY_RETRY_AFTER_SECONDS)},
+ ) from exc
+ except ImageTooLargeError as exc:
+ raise HTTPException(
+ status_code=status.HTTP_413_CONTENT_TOO_LARGE,
+ detail=str(exc),
+ ) from exc
+ except ImageDecodeError as exc:
+ raise HTTPException(
+ status_code=status.HTTP_422_UNPROCESSABLE_CONTENT,
+ detail=str(exc),
+ ) from exc
+
+ return CaptionResponse(
+ caption=caption,
+ model_version=service.model_version,
+ decode_strategy=decode_strategy or service.decode_strategy,
+ latency_ms=round(latency_ms, 2),
+ request_id=current_request_id(),
+ )
diff --git a/backend/app/core/__init__.py b/backend/app/core/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..1cbafc1e9e90ff64a3875db39cc233798af87314
--- /dev/null
+++ b/backend/app/core/__init__.py
@@ -0,0 +1,18 @@
+"""Core: backend settings and HTTP-layer logging glue."""
+
+from app.core.config import BackendSettings, get_backend_settings
+from app.core.logging import (
+ REQUEST_ID_HEADER,
+ RequestContextMiddleware,
+ configure_app_logging,
+ current_request_id,
+)
+
+__all__ = [
+ "REQUEST_ID_HEADER",
+ "BackendSettings",
+ "RequestContextMiddleware",
+ "configure_app_logging",
+ "current_request_id",
+ "get_backend_settings",
+]
diff --git a/backend/app/core/body_limit.py b/backend/app/core/body_limit.py
new file mode 100644
index 0000000000000000000000000000000000000000..48c7e72c7b956182469aa29fe31fdb970754cf34
--- /dev/null
+++ b/backend/app/core/body_limit.py
@@ -0,0 +1,71 @@
+"""Request-body size cap, enforced while the body is still arriving.
+
+FastAPI parses a multipart form before any route or dependency runs, and
+Starlette's parser reads the whole body, spooling file parts to a temporary
+file past 1 MiB. The route's own size check therefore runs only after an
+oversized upload has been received in full. This middleware rejects such a
+body first: as soon as the declared ``Content-Length``, or the bytes received
+so far, exceed the cap.
+
+It raises the same 413 ``HTTPException`` the route uses, from inside
+``receive()``. FastAPI re-raises an ``HTTPException`` that occurs while it
+reads the body, so the response keeps the route's ``{"detail": ...}`` shape
+and passes through the CORS and request-id middleware like any other error.
+"""
+
+from __future__ import annotations
+
+from starlette.exceptions import HTTPException
+from starlette.status import HTTP_413_CONTENT_TOO_LARGE
+from starlette.types import ASGIApp, Message, Receive, Scope, Send
+
+# Room for the multipart framing around the image: boundary lines and the
+# part's headers. The route still enforces the exact image-size limit.
+MULTIPART_OVERHEAD_BYTES = 64 * 1024
+
+
+class BodySizeLimitMiddleware:
+ """Reject request bodies larger than ``max_upload_bytes`` plus framing."""
+
+ def __init__(self, app: ASGIApp, *, max_upload_bytes: int) -> None:
+ self.app = app
+ self.max_upload_bytes = max_upload_bytes
+ self.max_body_bytes = max_upload_bytes + MULTIPART_OVERHEAD_BYTES
+
+ async def __call__(self, scope: Scope, receive: Receive, send: Send) -> None:
+ if scope["type"] != "http":
+ await self.app(scope, receive, send)
+ return
+
+ declared = _declared_length(scope)
+ received = 0
+
+ async def limited_receive() -> Message:
+ nonlocal received
+ if declared is not None and declared > self.max_body_bytes:
+ raise self._too_large()
+ message = await receive()
+ if message["type"] == "http.request":
+ received += len(message.get("body", b""))
+ if received > self.max_body_bytes:
+ raise self._too_large()
+ return message
+
+ await self.app(scope, limited_receive, send)
+
+ def _too_large(self) -> HTTPException:
+ return HTTPException(
+ status_code=HTTP_413_CONTENT_TOO_LARGE,
+ detail=f"Image exceeds the {self.max_upload_bytes}-byte upload limit.",
+ )
+
+
+def _declared_length(scope: Scope) -> int | None:
+ """Return the request's ``Content-Length``, or ``None`` if absent or invalid."""
+ for name, value in scope["headers"]:
+ if name == b"content-length":
+ try:
+ return int(value)
+ except ValueError:
+ return None
+ return None
diff --git a/backend/app/core/config.py b/backend/app/core/config.py
new file mode 100644
index 0000000000000000000000000000000000000000..7e8d109448d18ceec736d8c05770ad40e28b188f
--- /dev/null
+++ b/backend/app/core/config.py
@@ -0,0 +1,120 @@
+"""Backend runtime settings.
+
+These settings drive the FastAPI process itself: where to find the trained
+artifacts, what to advertise as the model version, whether to warm up at
+boot. They are intentionally separate from ``captioning.config.AppConfig``,
+which owns the *ML* configuration (architecture, decode strategy, CORS
+origins). Keeping the two layers split lets ops change deployment paths
+without touching research configs, and vice versa.
+
+Override any field via environment variable, prefixed with ``BACKEND_``::
+
+ BACKEND_CONFIG_PATH=configs/base.yaml
+ BACKEND_WEIGHTS_PATH=models/v1.0.0/model.h5
+ BACKEND_TOKENIZER_DIR=models/v1.0.0
+ BACKEND_MODEL_VERSION=v1.0.0
+ BACKEND_WARMUP=true
+ BACKEND_WEIGHTS_HUB_REPO=your-username/captioning-weights
+ BACKEND_WEIGHTS_HUB_REVISION=
+"""
+
+from __future__ import annotations
+
+from functools import lru_cache
+from pathlib import Path
+
+from pydantic import Field, field_validator
+from pydantic_settings import BaseSettings, SettingsConfigDict
+
+
+class BackendSettings(BaseSettings):
+ """Settings for the FastAPI inference service."""
+
+ config_path: Path = Field(
+ default=Path("configs/base.yaml"),
+ description="Path to the YAML AppConfig consumed by the ML package.",
+ )
+ weights_path: Path = Field(
+ default=Path("models/v1.0.0/model.h5"),
+ description="Path to the trained Keras weights file (used when weights_hub_repo is unset).",
+ )
+ tokenizer_dir: Path = Field(
+ default=Path("models/v1.0.0"),
+ description=(
+ "Directory containing vocab.json (or a legacy vocab.pkl) "
+ "(used when weights_hub_repo is unset)."
+ ),
+ )
+ model_version: str = Field(
+ default="v1.0.0",
+ description="Semantic version surfaced in /healthz and caption responses.",
+ )
+ api_version: str = Field(
+ default="0.1.0",
+ description="FastAPI app version (shown in OpenAPI docs).",
+ )
+ warmup: bool = Field(
+ default=True,
+ description="Run one dummy inference at startup so the first request is fast.",
+ )
+ request_id_header: str = Field(
+ default="x-request-id",
+ description="HTTP header used for request correlation IDs.",
+ )
+
+ # ---- HuggingFace Hub weights pull (WS-A4) -------------------------------
+ # When ``weights_hub_repo`` is set, ``lifespan`` calls
+ # ``huggingface_hub.snapshot_download`` for the weights file and vocab.json
+ # at an immutable commit, and resolves ``weights_path`` and
+ # ``tokenizer_dir`` to paths inside the downloaded snapshot. This lets the
+ # Docker image stay small and lets us rotate weights without rebuilding.
+ weights_hub_repo: str | None = Field(
+ default=None,
+ description="HuggingFace Hub repo id (e.g. 'user/captioning-weights'). None = use local paths.",
+ )
+ weights_hub_revision: str = Field(
+ default="main",
+ description=(
+ "Full 40-character Hub commit id, or a tag pinned in "
+ "app.services.weights_loader.PINNED_HUB_REVISIONS. Any other value, "
+ "including this 'main' default, is refused when weights_hub_repo is set, "
+ "and so is a commit without SHA-256 digests in PINNED_ARTIFACT_SHA256."
+ ),
+ )
+ weights_hub_filename: str = Field(
+ default="model.h5",
+ description="Filename of the weights file inside the Hub snapshot.",
+ )
+ weights_cache_dir: Path | None = Field(
+ default=None,
+ description="Local cache dir for snapshot_download. None = HF Hub default ($HF_HOME).",
+ )
+
+ model_config = SettingsConfigDict(
+ env_prefix="BACKEND_",
+ case_sensitive=False,
+ extra="ignore",
+ # ``model_version`` would otherwise warn about pydantic's ``model_``
+ # namespace on every import; ``settings_`` stays protected.
+ protected_namespaces=("settings_",),
+ )
+
+ @field_validator("config_path", "weights_path", "tokenizer_dir")
+ @classmethod
+ def _expand_user(cls, value: Path) -> Path:
+ return value.expanduser()
+
+ @field_validator("weights_cache_dir")
+ @classmethod
+ def _expand_optional_user(cls, value: Path | None) -> Path | None:
+ return value.expanduser() if value is not None else None
+
+
+@lru_cache(maxsize=1)
+def get_backend_settings() -> BackendSettings:
+ """Return a process-wide ``BackendSettings`` instance.
+
+ Cached so env-var parsing happens once. Tests that need to override env
+ can call ``get_backend_settings.cache_clear()`` between cases.
+ """
+ return BackendSettings()
diff --git a/backend/app/core/logging.py b/backend/app/core/logging.py
new file mode 100644
index 0000000000000000000000000000000000000000..977045b14a071f3d5d9b9883b634c0067b464a42
--- /dev/null
+++ b/backend/app/core/logging.py
@@ -0,0 +1,87 @@
+"""HTTP-layer logging glue.
+
+The ML package already configures structlog (``captioning.utils.logging``).
+The FastAPI process has two extra needs on top of that:
+
+1. **Request correlation** — every log line emitted while handling a
+ request should carry the same ``request_id`` so logs can be grouped.
+ We bind it once via ``structlog.contextvars`` so any ``log.info(...)``
+ downstream automatically inherits it without threading the id through
+ function signatures.
+
+2. **Access logs as structured events** — uvicorn's default access log is
+ a plain string. Re-emitting one structured ``request_finished`` event
+ per request keeps the log stream homogeneous and indexable.
+"""
+
+from __future__ import annotations
+
+import time
+import uuid
+from collections.abc import Awaitable, Callable
+
+import structlog
+from starlette.middleware.base import BaseHTTPMiddleware
+from starlette.requests import Request
+from starlette.responses import Response
+
+from captioning.utils.logging import configure_logging, get_logger
+
+log = get_logger(__name__)
+
+REQUEST_ID_HEADER = "x-request-id"
+
+
+def configure_app_logging() -> None:
+ """Initialise structlog for the FastAPI process.
+
+ Idempotent — delegates to the ML package's ``configure_logging`` so dev
+ gets pretty colourised output and ``APP_ENV=production`` flips to JSON.
+ """
+ configure_logging()
+
+
+class RequestContextMiddleware(BaseHTTPMiddleware):
+ """Bind a request id to structlog and log start/finish events.
+
+ The id comes from the inbound ``x-request-id`` header when present
+ (so an upstream gateway can stitch traces), or a fresh ``uuid4`` hex
+ otherwise. Either way it's echoed back on the response.
+ """
+
+ async def dispatch(
+ self,
+ request: Request,
+ call_next: Callable[[Request], Awaitable[Response]],
+ ) -> Response:
+ request_id = request.headers.get(REQUEST_ID_HEADER) or uuid.uuid4().hex
+
+ structlog.contextvars.clear_contextvars()
+ structlog.contextvars.bind_contextvars(
+ request_id=request_id,
+ method=request.method,
+ path=request.url.path,
+ )
+
+ start = time.perf_counter()
+ log.info("request_started")
+ try:
+ response = await call_next(request)
+ except Exception:
+ duration_ms = (time.perf_counter() - start) * 1000
+ log.exception("request_failed", duration_ms=round(duration_ms, 2))
+ raise
+
+ duration_ms = (time.perf_counter() - start) * 1000
+ log.info(
+ "request_finished",
+ status=response.status_code,
+ duration_ms=round(duration_ms, 2),
+ )
+ response.headers[REQUEST_ID_HEADER] = request_id
+ return response
+
+
+def current_request_id() -> str:
+ """Return the request id bound to the current contextvars, or ``""``."""
+ return str(structlog.contextvars.get_contextvars().get("request_id", ""))
diff --git a/backend/app/main.py b/backend/app/main.py
new file mode 100644
index 0000000000000000000000000000000000000000..42059ae44d39178da2c7d56874c0555e3d5cd311
--- /dev/null
+++ b/backend/app/main.py
@@ -0,0 +1,110 @@
+"""FastAPI application entrypoint.
+
+Run locally with::
+
+ uvicorn --app-dir backend app.main:app --host 0.0.0.0 --port 8000 --reload
+
+Lifespan order:
+ 1. Load YAML ``AppConfig`` (research-side hyperparameters).
+ 2. Load weights + tokenizer into a ``CaptionPredictor`` singleton.
+ 3. Optionally warmup so the first request doesn't pay TF's lazy build cost.
+ 4. Wrap the predictor in a ``PredictorService`` and stash on app state.
+
+The singleton lives on ``app.state.predictor_service``; routes pull it
+through a ``Depends`` so tests can override the dependency cleanly.
+"""
+
+from __future__ import annotations
+
+from collections.abc import AsyncIterator
+from contextlib import asynccontextmanager
+
+from fastapi import FastAPI
+from fastapi.middleware.cors import CORSMiddleware
+
+from app.api.routes import router
+from app.core.body_limit import BodySizeLimitMiddleware
+from app.core.config import BackendSettings, get_backend_settings
+from app.core.logging import RequestContextMiddleware, configure_app_logging
+from app.services.predictor_service import PredictorService
+from app.services.weights_loader import resolve_weights
+from captioning.config import load_config
+from captioning.config.schema import AppConfig
+from captioning.inference import CaptionPredictor
+from captioning.utils import get_logger
+
+log = get_logger(__name__)
+
+
+@asynccontextmanager
+async def lifespan(app: FastAPI) -> AsyncIterator[None]:
+ """Load the predictor at startup, release it at shutdown."""
+ settings: BackendSettings = app.state.backend_settings
+ config: AppConfig = app.state.app_config
+
+ weights_path, tokenizer_dir = resolve_weights(settings)
+
+ log.info(
+ "predictor_loading",
+ weights=str(weights_path),
+ tokenizer_dir=str(tokenizer_dir),
+ model_version=settings.model_version,
+ )
+
+ predictor = CaptionPredictor.from_artifacts(
+ weights_path=weights_path,
+ tokenizer_dir=tokenizer_dir,
+ config=config,
+ )
+ if settings.warmup:
+ predictor.warmup()
+
+ app.state.predictor_service = PredictorService(
+ predictor=predictor,
+ model_version=settings.model_version,
+ max_upload_bytes=config.serve.max_upload_bytes,
+ )
+ log.info("predictor_ready", model_version=settings.model_version)
+
+ try:
+ yield
+ finally:
+ app.state.predictor_service = None
+ log.info("predictor_unloaded")
+
+
+def create_app() -> FastAPI:
+ """Build the FastAPI app. Factory form so tests can construct fresh apps."""
+ configure_app_logging()
+ settings = get_backend_settings()
+ config = load_config(settings.config_path)
+
+ app = FastAPI(
+ title="Image Captioning API",
+ version=settings.api_version,
+ description=(
+ "Production-grade inference service for the IEEE-published "
+ "CNN+Transformer image captioning model."
+ ),
+ lifespan=lifespan,
+ )
+
+ app.state.backend_settings = settings
+ app.state.app_config = config
+ app.state.predictor_service = None
+
+ app.add_middleware(BodySizeLimitMiddleware, max_upload_bytes=config.serve.max_upload_bytes)
+ app.add_middleware(
+ CORSMiddleware,
+ allow_origins=config.serve.cors_allowed_origins,
+ allow_methods=["GET", "POST", "OPTIONS"],
+ allow_headers=["*"],
+ allow_credentials=False,
+ )
+ app.add_middleware(RequestContextMiddleware)
+
+ app.include_router(router)
+ return app
+
+
+app = create_app()
diff --git a/backend/app/schemas/__init__.py b/backend/app/schemas/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..93220f1cd0d5bdf3c309bcc218847c410b427e52
--- /dev/null
+++ b/backend/app/schemas/__init__.py
@@ -0,0 +1,5 @@
+"""Pydantic request/response schemas."""
+
+from app.schemas.caption import CaptionResponse, ErrorResponse, HealthResponse
+
+__all__ = ["CaptionResponse", "ErrorResponse", "HealthResponse"]
diff --git a/backend/app/schemas/caption.py b/backend/app/schemas/caption.py
new file mode 100644
index 0000000000000000000000000000000000000000..a5ba27c652ce5603e94df2774ecdb68befd714c8
--- /dev/null
+++ b/backend/app/schemas/caption.py
@@ -0,0 +1,65 @@
+"""Pydantic request/response models for the captioning API.
+
+Schemas live separately from routes so the OpenAPI spec is stable even
+when handler logic changes. Every field is annotated with an example so
+``/docs`` is self-explanatory to anyone reviewing the portfolio.
+"""
+
+from __future__ import annotations
+
+from datetime import datetime
+
+from pydantic import BaseModel, ConfigDict, Field
+
+
+class HealthResponse(BaseModel):
+ """Liveness + readiness payload for ``GET /healthz``."""
+
+ status: str = Field(..., description="``ok`` once the predictor is loaded.")
+ model_loaded: bool = Field(..., description="True after weights + tokenizer are in memory.")
+ model_version: str = Field(..., description="Semantic version of the served model.")
+ api_version: str = Field(..., description="Backend release version.")
+ timestamp: datetime = Field(..., description="Server time the response was built (UTC).")
+
+ model_config = ConfigDict(
+ protected_namespaces=(),
+ json_schema_extra={
+ "example": {
+ "status": "ok",
+ "model_loaded": True,
+ "model_version": "v1.0.0",
+ "api_version": "0.1.0",
+ "timestamp": "2026-05-09T12:00:00Z",
+ }
+ },
+ )
+
+
+class CaptionResponse(BaseModel):
+ """Successful response from ``POST /v1/captions``."""
+
+ caption: str = Field(..., description="Generated caption text (without start/end tokens).")
+ model_version: str = Field(..., description="Model version that produced this caption.")
+ decode_strategy: str = Field(..., description="Decoding strategy used (e.g. ``greedy``).")
+ latency_ms: float = Field(..., description="Inference time in milliseconds.")
+ request_id: str = Field(..., description="Correlation id; matches the ``x-request-id`` header.")
+
+ model_config = ConfigDict(
+ protected_namespaces=(),
+ json_schema_extra={
+ "example": {
+ "caption": "a man riding a surfboard on a wave",
+ "model_version": "v1.0.0",
+ "decode_strategy": "greedy",
+ "latency_ms": 187.42,
+ "request_id": "8f1c2e3b4d5a4f8e9b0c1d2e3f4a5b6c",
+ }
+ },
+ )
+
+
+class ErrorResponse(BaseModel):
+ """Uniform error envelope returned by every non-2xx status."""
+
+ detail: str = Field(..., description="Human-readable error message.")
+ request_id: str = Field(default="", description="Correlation id for log lookup.")
diff --git a/backend/app/services/__init__.py b/backend/app/services/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..2a848634cdf4640e6d3d81f3acc5cb691bd85c7e
--- /dev/null
+++ b/backend/app/services/__init__.py
@@ -0,0 +1,5 @@
+"""Service layer wrapping the ML predictor."""
+
+from app.services.predictor_service import PredictorService
+
+__all__ = ["PredictorService"]
diff --git a/backend/app/services/predictor_service.py b/backend/app/services/predictor_service.py
new file mode 100644
index 0000000000000000000000000000000000000000..062087ed4cc2d7ec4885be6ca4c0afac743f8463
--- /dev/null
+++ b/backend/app/services/predictor_service.py
@@ -0,0 +1,145 @@
+"""Service layer wrapping the ML ``CaptionPredictor``.
+
+Why this exists between the route and the predictor:
+ * **Off-loop execution** — TensorFlow inference is sync and CPU-bound.
+ Running it inline blocks the event loop, so requests queue up
+ sequentially and event-loop-bound work (CORS, metrics, /healthz)
+ stalls. We push the call to a worker thread via ``anyio.to_thread``.
+ * **Bounded admission** — at most ``max_concurrent_inferences`` requests
+ decode or predict at once. The next one is refused straight away
+ (``PredictorBusyError``, a 503 at the route) instead of waiting.
+ * **Stable seam for testing** — routes depend on this class, not on
+ the concrete predictor. Tests can substitute a stub service that
+ returns canned captions without loading TensorFlow.
+ * **Future extension point** — Phase 4 will add a request batcher and
+ per-model registry behind the same ``caption_image_bytes`` API.
+
+This class never re-implements inference; it delegates entirely to the
+existing ``CaptionPredictor`` abstraction.
+"""
+
+from __future__ import annotations
+
+import time
+from functools import partial
+
+from anyio import to_thread
+
+from app.utils.image import bytes_to_tensor
+from captioning.inference import CaptionPredictor
+from captioning.inference.predictor import DECODE_STRATEGIES
+from captioning.utils import get_logger
+
+log = get_logger(__name__)
+
+__all__ = [
+ "DECODE_STRATEGIES",
+ "MAX_CONCURRENT_INFERENCES",
+ "PredictorBusyError",
+ "PredictorService",
+]
+
+# Requests allowed to decode or predict at once. The Space runs on HF's
+# cpu-basic tier (2 vCPU), and TensorFlow already spreads one inference across
+# both cores, so more parallel inferences would compete for CPU rather than add
+# throughput. Two also bounds the decode working set to about 1.2 GB by the
+# TASK-026 estimate (~600 MB per image at the pixel limit). Chosen from the
+# hardware, not benchmarked.
+MAX_CONCURRENT_INFERENCES = 2
+
+
+class PredictorBusyError(RuntimeError):
+ """Raised when every inference slot is in use. The request isn't queued."""
+
+
+class PredictorService:
+ """Holds the singleton predictor and exposes async inference."""
+
+ def __init__(
+ self,
+ *,
+ predictor: CaptionPredictor,
+ model_version: str,
+ max_upload_bytes: int,
+ max_concurrent_inferences: int = MAX_CONCURRENT_INFERENCES,
+ ) -> None:
+ """Args:
+ predictor: A ready ``CaptionPredictor`` (weights already loaded).
+ model_version: Semver string surfaced in responses & health.
+ max_upload_bytes: Hard cap enforced at the route layer.
+ max_concurrent_inferences: Inference slots; at least 1.
+ """
+ if max_concurrent_inferences < 1:
+ raise ValueError(
+ f"max_concurrent_inferences must be >= 1, got {max_concurrent_inferences}"
+ )
+ self._predictor = predictor
+ self._model_version = model_version
+ self._max_upload_bytes = max_upload_bytes
+ self._max_concurrent = max_concurrent_inferences
+ self._in_flight = 0
+
+ @property
+ def model_version(self) -> str:
+ return self._model_version
+
+ @property
+ def decode_strategy(self) -> str:
+ return self._predictor.decode_strategy
+
+ @property
+ def max_upload_bytes(self) -> int:
+ return self._max_upload_bytes
+
+ @property
+ def inferences_in_flight(self) -> int:
+ """Requests holding a slot, including cancelled ones whose thread still runs."""
+ return self._in_flight
+
+ async def caption_image_bytes(
+ self, image_bytes: bytes, *, decode_strategy: str | None = None
+ ) -> tuple[str, float]:
+ """Decode bytes, run inference, and return (caption, latency_ms).
+
+ ``decode_strategy`` applies to this call only; ``None`` means the
+ predictor's default. The route validates the value first.
+
+ Both the decode and the predict are offloaded to a worker thread so
+ the event loop stays responsive. Latency is measured around the
+ predict call only — decode timing belongs to a separate span if we
+ ever need it.
+
+ Admission: the slot check and the increment run on the event loop
+ with no ``await`` between them, so two requests can't both take the
+ last slot. ``finally`` gives the slot back on every exit path.
+
+ Cancellation: ``to_thread.run_sync`` keeps its default
+ ``abandon_on_cancel=False``, so a cancelled caller (a client
+ disconnect, for instance) still waits for the worker thread it
+ started, and its slot is freed only when that thread has finished.
+ Cancelling doesn't stop TensorFlow work that is already running.
+
+ Raises:
+ PredictorBusyError: If every slot is in use. Nothing is decoded.
+ """
+ if self._in_flight >= self._max_concurrent:
+ raise PredictorBusyError("All inference slots are in use.")
+ self._in_flight += 1
+ try:
+ tensor = await to_thread.run_sync(bytes_to_tensor, image_bytes)
+
+ start = time.perf_counter()
+ caption: str = await to_thread.run_sync(
+ partial(self._predictor.predict_tensor, tensor, decode_strategy=decode_strategy)
+ )
+ latency_ms = (time.perf_counter() - start) * 1000
+ finally:
+ self._in_flight -= 1
+
+ log.info(
+ "inference_completed",
+ model_version=self._model_version,
+ decode_strategy=decode_strategy or self.decode_strategy,
+ latency_ms=round(latency_ms, 2),
+ )
+ return caption, latency_ms
diff --git a/backend/app/services/weights_loader.py b/backend/app/services/weights_loader.py
new file mode 100644
index 0000000000000000000000000000000000000000..00e1ecc02c3d0cf6d16bca2605225b602309dd4d
--- /dev/null
+++ b/backend/app/services/weights_loader.py
@@ -0,0 +1,257 @@
+"""Resolve weights and tokenizer paths, optionally pulling from HuggingFace Hub.
+
+In production we don't want to bake a 158 MB ``.h5`` file into the Docker
+image — it makes builds slow and couples weight rotation to image rebuilds.
+Instead, the image carries only code, and the runtime pulls the weights file
+and ``vocab.json`` from a public Hub repo, at an immutable commit, the first
+time the container boots. On HuggingFace Spaces the cache persists across
+restarts. Both files are checked against SHA-256 digests pinned for that
+commit before their paths are returned. The loaders reopen them by path, so
+the check covers the cache as it was at that moment.
+
+When ``BackendSettings.weights_hub_repo`` is unset we fall back to the
+local paths declared in settings, which is what unit tests and `make serve`
+use today. Local files aren't hashed.
+"""
+
+from __future__ import annotations
+
+import hashlib
+import re
+from pathlib import Path
+from typing import Protocol
+
+from app.core.config import BackendSettings
+from captioning.preprocessing.tokenizer import VOCAB_JSON_FILENAME
+from captioning.utils import get_logger
+
+log = get_logger(__name__)
+
+# A full Hub commit id. Branches and tags can be moved to another commit; a
+# commit id can't.
+_COMMIT_ID = re.compile(r"[0-9a-f]{40}")
+
+# Published tags and the commit each one named when it was evaluated and
+# deployed (checked against the Hub API on 2026-10-12). The loader downloads the
+# commit recorded here, never the tag, so moving a tag on the Hub changes
+# nothing. A new tag needs a new line here before a Space variable can name it.
+PINNED_HUB_REVISIONS: dict[tuple[str, str], str] = {
+ (
+ "apoorvrajdev/captioning-inceptionv3-transformer",
+ "v1.0.0",
+ ): "d917a47decc1f352e50ba4226e92ca5f00d47e9a",
+ (
+ "apoorvrajdev/captioning-inceptionv3-transformer",
+ "v2.0.0",
+ ): "59d93b4babb16b0ac81eef598f3abc271a355cbf",
+}
+
+# A lower-case hex SHA-256 digest, the form hashlib and Git LFS pointers use.
+_SHA256 = re.compile(r"[0-9a-f]{64}")
+
+# SHA-256 of every file serving reads, per repo and commit. A commit without an
+# entry here, or a file missing from its entry, is refused before any download.
+# Provenance (Hub API, read-only, 2026-10-12):
+# - model.h5 is a Git LFS file. Its digest is the ``oid sha256`` of the LFS
+# pointer stored in the commit's tree, and that pointer's git blob id matches
+# the tree entry. v2.0.0's digest also appears in docs/EVAL_METHODOLOGY.md
+# (2026-10-06).
+# - vocab.json is a plain git file, for which the Hub publishes only a SHA-1
+# blob id. Its digest is the SHA-256 of bytes whose git blob id matched the
+# commit's tree entry (v1.0.0 f8ce580…, v2.0.0 1a437e1…). v1.0.0's also equals
+# the repo's own models/v1.0.0/vocab.json.
+# Serving a new commit means adding its digests here, from the same sources,
+# and deploying that first.
+PINNED_ARTIFACT_SHA256: dict[tuple[str, str], dict[str, str]] = {
+ (
+ "apoorvrajdev/captioning-inceptionv3-transformer",
+ "d917a47decc1f352e50ba4226e92ca5f00d47e9a", # v1.0.0
+ ): {
+ "model.h5": "bfe020d920aa2f3d019bf7b5b33904384057372e7c304a9e101a2a59fe110084",
+ "vocab.json": "45ec1704d73046303cbd5292590b2e204b194a2d8345dfb84de81370b4ab4eef",
+ },
+ (
+ "apoorvrajdev/captioning-inceptionv3-transformer",
+ "59d93b4babb16b0ac81eef598f3abc271a355cbf", # v2.0.0
+ ): {
+ "model.h5": "74963a3f7cd01b16f44cd179f1e21e9eb8d60b52d460e517cdcf38c015689b07",
+ "vocab.json": "4315c5a7350d6052dbc120e02d218b9a95a23797aa24ec5670824eb6667d2886",
+ },
+}
+
+
+class ArtifactIntegrityError(RuntimeError):
+ """A downloaded file's SHA-256 differs from the digest pinned for its commit."""
+
+
+class SnapshotDownloader(Protocol):
+ """Minimal callable shape we need from ``huggingface_hub.snapshot_download``."""
+
+ def __call__(
+ self,
+ *,
+ repo_id: str,
+ revision: str,
+ cache_dir: str | None,
+ allow_patterns: list[str],
+ ) -> str: ...
+
+
+def resolve_hub_commit(repo_id: str, revision: str) -> str:
+ """Return the immutable commit id to download for ``revision``.
+
+ A full 40-character commit id is used as given. A tag listed in
+ ``PINNED_HUB_REVISIONS`` for ``repo_id`` resolves to its recorded commit.
+ Anything else, including a branch such as ``main``, raises ``ValueError``.
+ """
+ if _COMMIT_ID.fullmatch(revision):
+ return revision
+ pinned = PINNED_HUB_REVISIONS.get((repo_id, revision))
+ if pinned is None:
+ raise ValueError(
+ f"BACKEND_WEIGHTS_HUB_REVISION={revision!r} is neither a full 40-character "
+ f"commit id nor a tag of {repo_id} pinned in "
+ "app.services.weights_loader.PINNED_HUB_REVISIONS. Set it to the commit id "
+ "(HfApi().model_info(repo_id, revision=tag).sha) or pin the tag first."
+ )
+ return pinned
+
+
+def pinned_sha256(repo_id: str, commit: str, filenames: list[str]) -> dict[str, str]:
+ """Return the pinned SHA-256 of each of ``filenames`` at ``commit``.
+
+ Raises ``ValueError`` when the commit has no entry in
+ ``PINNED_ARTIFACT_SHA256``, when a file has no digest there, or when a
+ digest isn't 64 lower-case hex characters. Callers run this before
+ downloading, so an unverifiable revision never reaches the network.
+ """
+ pinned = PINNED_ARTIFACT_SHA256.get((repo_id, commit))
+ if pinned is None:
+ raise ValueError(
+ f"Hub commit {commit} of {repo_id} has no SHA-256 digests in "
+ "app.services.weights_loader.PINNED_ARTIFACT_SHA256, so its files can't be "
+ "verified. Add the digests for that commit (see the comment above the table) "
+ "and deploy them before serving it."
+ )
+ expected: dict[str, str] = {}
+ for name in filenames:
+ digest = pinned.get(name)
+ if digest is None:
+ raise ValueError(
+ f"PINNED_ARTIFACT_SHA256 has no SHA-256 for {name} at Hub commit {commit} "
+ f"of {repo_id}. Pin a digest for every file serving reads."
+ )
+ if not _SHA256.fullmatch(digest):
+ raise ValueError(
+ f"PINNED_ARTIFACT_SHA256 holds a malformed SHA-256 for {name} at Hub commit "
+ f"{commit} of {repo_id}: expected 64 lower-case hex characters."
+ )
+ expected[name] = digest
+ return expected
+
+
+def sha256_file(path: Path, chunk_size: int = 1 << 20) -> str:
+ """Return the hex SHA-256 of ``path``, read in chunks so memory stays bounded."""
+ digest = hashlib.sha256()
+ with path.open("rb") as f:
+ while chunk := f.read(chunk_size):
+ digest.update(chunk)
+ return digest.hexdigest()
+
+
+def verify_sha256(directory: Path, expected: dict[str, str], *, repo_id: str, commit: str) -> None:
+ """Check every file in ``expected`` under ``directory`` against its digest.
+
+ Every file is hashed, even after a mismatch, so the error lists each file
+ that differs.
+
+ Raises:
+ ArtifactIntegrityError: One or more files differ from their digest.
+ """
+ mismatches = []
+ for name, want in expected.items():
+ got = sha256_file(directory / name)
+ if got != want:
+ mismatches.append(f"{name} has SHA-256 {got}, expected {want}")
+ if mismatches:
+ raise ArtifactIntegrityError(
+ f"Hub commit {commit} of {repo_id} failed verification in {directory}: "
+ f"{'; '.join(mismatches)}. Nothing was loaded. The download or the local "
+ "cache is corrupt or was altered: delete the file from the Hub cache, both "
+ "the snapshot entry and the blob it links to, and restart to download it "
+ "again. If it still fails, the Hub no longer serves the pinned bytes; don't "
+ "serve this revision."
+ )
+
+
+def resolve_weights(
+ settings: BackendSettings,
+ downloader: SnapshotDownloader | None = None,
+) -> tuple[Path, Path]:
+ """Return ``(weights_path, tokenizer_dir)`` for the predictor to load.
+
+ Local mode (``weights_hub_repo`` is None): returns the paths verbatim.
+
+ Hub mode: resolves the configured revision to a commit id, looks up the
+ SHA-256 pinned for each file at that commit, downloads only the weights
+ file and ``vocab.json`` at that commit, checks both against their digests,
+ then returns paths inside the snapshot directory. The downloader is
+ injectable so tests can substitute a stub instead of hitting the network.
+
+ Raises:
+ ValueError: The revision is not a commit id or a pinned tag, or the
+ commit has no valid pinned digest for a file.
+ FileNotFoundError: The commit lacks the weights file or ``vocab.json``.
+ ArtifactIntegrityError: A downloaded file differs from its digest.
+ """
+ if not settings.weights_hub_repo:
+ log.info(
+ "weights_source_local",
+ weights=str(settings.weights_path),
+ tokenizer_dir=str(settings.tokenizer_dir),
+ )
+ return settings.weights_path, settings.tokenizer_dir
+
+ commit = resolve_hub_commit(settings.weights_hub_repo, settings.weights_hub_revision)
+ required = [settings.weights_hub_filename, VOCAB_JSON_FILENAME]
+ expected = pinned_sha256(settings.weights_hub_repo, commit, required)
+
+ if downloader is None:
+ from huggingface_hub import snapshot_download as _snapshot_download
+
+ downloader = _snapshot_download
+ assert downloader is not None # for type-checker
+
+ cache_dir = str(settings.weights_cache_dir) if settings.weights_cache_dir else None
+ log.info(
+ "weights_source_hub",
+ repo=settings.weights_hub_repo,
+ revision=settings.weights_hub_revision,
+ commit=commit,
+ files=required,
+ cache_dir=cache_dir,
+ )
+ snapshot_dir = Path(
+ downloader(
+ repo_id=settings.weights_hub_repo,
+ revision=commit,
+ cache_dir=cache_dir,
+ allow_patterns=required,
+ )
+ )
+ missing = [name for name in required if not (snapshot_dir / name).is_file()]
+ if missing:
+ raise FileNotFoundError(
+ f"Hub commit {commit} of {settings.weights_hub_repo} has no "
+ f"{', '.join(missing)}. Serving needs the weights file and "
+ f"{VOCAB_JSON_FILENAME} at the same commit."
+ )
+ verify_sha256(snapshot_dir, expected, repo_id=settings.weights_hub_repo, commit=commit)
+ weights_path = snapshot_dir / settings.weights_hub_filename
+ log.info(
+ "weights_verified",
+ snapshot_dir=str(snapshot_dir),
+ weights=str(weights_path),
+ sha256=expected,
+ )
+ return weights_path, snapshot_dir
diff --git a/backend/app/tests/__init__.py b/backend/app/tests/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..e69de29bb2d1d6434b8b29ae775ad8c2e48c5391
diff --git a/backend/app/tests/conftest.py b/backend/app/tests/conftest.py
new file mode 100644
index 0000000000000000000000000000000000000000..28a425279ae635e9ed741b5985c02c7fb1f21c86
--- /dev/null
+++ b/backend/app/tests/conftest.py
@@ -0,0 +1,101 @@
+"""Shared fixtures for the backend test suite.
+
+These tests deliberately avoid loading TensorFlow or any real model.
+The route layer depends on ``PredictorService`` only through duck-typed
+attributes (``model_version``, ``decode_strategy``, ``max_upload_bytes``,
+``caption_image_bytes``), so a small fake stands in cleanly and keeps the
+whole suite under one second.
+
+We also bypass the FastAPI lifespan entirely. The lifespan builds a real
+``CaptionPredictor`` from disk, which requires weights, a tokenizer, and a
+TF graph build. Tests build a fresh ``FastAPI`` instance, wire the same
+router and middleware, and stash the fake service directly on
+``app.state.predictor_service`` — the exact slot the lifespan would have
+populated in production.
+"""
+
+from __future__ import annotations
+
+from collections.abc import Callable, Iterator
+
+import pytest
+from fastapi import FastAPI
+from fastapi.testclient import TestClient
+
+from app.api.routes import router
+from app.core.config import BackendSettings
+from app.core.logging import RequestContextMiddleware, configure_app_logging
+from app.utils.image import ImageDecodeError, check_image_dimensions
+
+configure_app_logging()
+
+
+class FakePredictorService:
+ """Duck-typed stand-in for ``PredictorService``."""
+
+ def __init__(
+ self,
+ *,
+ caption: str = "a test caption",
+ latency_ms: float = 1.23,
+ decode_strategy: str = "greedy",
+ model_version: str = "test-v0",
+ max_upload_bytes: int = 1024,
+ raise_decode_error: bool = False,
+ check_dimensions: bool = False,
+ ) -> None:
+ self.model_version = model_version
+ self.decode_strategy = decode_strategy
+ self.max_upload_bytes = max_upload_bytes
+ self._caption = caption
+ self._latency_ms = latency_ms
+ self._raise = raise_decode_error
+ self._check_dimensions = check_dimensions
+ self.calls: list[bytes] = []
+ self.strategies: list[str | None] = []
+
+ async def caption_image_bytes(
+ self, image_bytes: bytes, *, decode_strategy: str | None = None
+ ) -> tuple[str, float]:
+ self.calls.append(image_bytes)
+ self.strategies.append(decode_strategy)
+ if self._raise:
+ raise ImageDecodeError("synthetic decode failure")
+ if self._check_dimensions:
+ # The real header guard that ``bytes_to_tensor`` runs first, without TF.
+ check_image_dimensions(image_bytes)
+ return self._caption, self._latency_ms
+
+
+def _build_app(service: FakePredictorService | None) -> FastAPI:
+ app = FastAPI()
+ app.state.backend_settings = BackendSettings()
+ app.state.predictor_service = service
+ app.add_middleware(RequestContextMiddleware)
+ app.include_router(router)
+ return app
+
+
+@pytest.fixture
+def fake_service() -> FakePredictorService:
+ return FakePredictorService()
+
+
+@pytest.fixture
+def client(fake_service: FakePredictorService) -> Iterator[TestClient]:
+ with TestClient(_build_app(fake_service)) as test_client:
+ yield test_client
+
+
+@pytest.fixture
+def client_without_service() -> Iterator[TestClient]:
+ with TestClient(_build_app(None)) as test_client:
+ yield test_client
+
+
+@pytest.fixture
+def build_client() -> Callable[[FakePredictorService | None], TestClient]:
+ def _make(service: FakePredictorService | None) -> TestClient:
+ return TestClient(_build_app(service))
+
+ return _make
diff --git a/backend/app/tests/image_bytes.py b/backend/app/tests/image_bytes.py
new file mode 100644
index 0000000000000000000000000000000000000000..9d2923890f1e8bda61f3459ec481058aeec97838
--- /dev/null
+++ b/backend/app/tests/image_bytes.py
@@ -0,0 +1,47 @@
+"""Small image byte builders for the upload dimension-guard tests.
+
+A header-only image declares any size in a few dozen bytes, so tests can check
+huge dimensions without allocating them. Nothing here decodes pixels.
+"""
+
+from __future__ import annotations
+
+import io
+import struct
+import zlib
+
+from PIL import Image
+
+
+def encode(fmt: str, size: tuple[int, int] = (32, 24), mode: str = "RGB") -> bytes:
+ """A small deterministic gradient image, saved as ``fmt``."""
+ width, height = size
+ pixels = bytes(
+ (x * 7 + y * 13 + channel * 50) % 256
+ for y in range(height)
+ for x in range(width)
+ for channel in range(3)
+ )
+ image = Image.frombytes("RGB", size, pixels).convert(mode)
+ buffer = io.BytesIO()
+ image.save(buffer, format=fmt)
+ return buffer.getvalue()
+
+
+def png_header(width: int, height: int) -> bytes:
+ """A structurally valid PNG that declares ``width`` x ``height`` and holds no pixels."""
+
+ def chunk(kind: bytes, data: bytes) -> bytes:
+ crc = zlib.crc32(kind + data)
+ return struct.pack(">I", len(data)) + kind + data + struct.pack(">I", crc)
+
+ ihdr = struct.pack(">IIBBBBB", width, height, 8, 2, 0, 0, 0) # 8-bit RGB
+ return b"\x89PNG\r\n\x1a\n" + chunk(b"IHDR", ihdr) + chunk(b"IDAT", b"") + chunk(b"IEND", b"")
+
+
+def jpeg_header(width: int, height: int) -> bytes:
+ """A baseline JPEG header (SOI, SOF0, SOS) for ``width`` x ``height``, with no scan data."""
+ components = b"\x01\x22\x00\x02\x11\x01\x03\x11\x01" # Y, Cb, Cr
+ sof0 = b"\xff\xc0" + struct.pack(">HBHHB", 17, 8, height, width, 3) + components
+ sos = b"\xff\xda" + struct.pack(">HB", 12, 3) + b"\x01\x00\x02\x11\x03\x11\x00\x3f\x00"
+ return b"\xff\xd8" + sof0 + sos
diff --git a/backend/app/tests/test_backend_settings.py b/backend/app/tests/test_backend_settings.py
new file mode 100644
index 0000000000000000000000000000000000000000..975cc1583132854c0d2ad1373909f2e6bc39ccf8
--- /dev/null
+++ b/backend/app/tests/test_backend_settings.py
@@ -0,0 +1,34 @@
+"""``BackendSettings`` imports cleanly and keeps its ``BACKEND_*`` field names."""
+
+from __future__ import annotations
+
+import subprocess
+import sys
+from pathlib import Path
+
+import pytest
+
+from app.core.config import BackendSettings
+
+BACKEND_DIR = Path(__file__).resolve().parents[2]
+
+
+def test_importing_the_settings_emits_no_user_warning() -> None:
+ """A fresh interpreter, because the warning fires once, when the class is defined."""
+ result = subprocess.run(
+ [sys.executable, "-W", "error::UserWarning", "-c", "import app.core.config"],
+ cwd=BACKEND_DIR,
+ capture_output=True,
+ text=True,
+ check=False,
+ )
+
+ assert result.returncode == 0, result.stderr
+
+
+def test_model_version_still_reads_its_environment_variable(
+ monkeypatch: pytest.MonkeyPatch,
+) -> None:
+ monkeypatch.setenv("BACKEND_MODEL_VERSION", "v9.9.9")
+
+ assert BackendSettings().model_version == "v9.9.9"
diff --git a/backend/app/tests/test_body_size_limit.py b/backend/app/tests/test_body_size_limit.py
new file mode 100644
index 0000000000000000000000000000000000000000..782ff7138cbd6bd482062172ed230cc6ec561fc0
--- /dev/null
+++ b/backend/app/tests/test_body_size_limit.py
@@ -0,0 +1,207 @@
+"""Tests for ``BodySizeLimitMiddleware`` on ``POST /v1/captions``.
+
+An oversized body must get the route's 413 before the multipart parser reads
+it, whether or not the client declares ``Content-Length``. The app is driven
+through raw ASGI, with the body handed over in 64 KiB chunks as uvicorn does,
+so each test can count how much of the body the app actually read.
+"""
+
+from __future__ import annotations
+
+import json
+import tempfile
+import weakref
+from collections.abc import Callable
+from typing import Any
+
+import anyio
+import pytest
+from fastapi import FastAPI
+from fastapi.middleware.cors import CORSMiddleware
+from starlette.types import Message
+
+from app.api.routes import router
+from app.core.body_limit import MULTIPART_OVERHEAD_BYTES, BodySizeLimitMiddleware
+from app.core.config import BackendSettings
+from app.core.logging import REQUEST_ID_HEADER, RequestContextMiddleware
+from app.tests.conftest import FakePredictorService
+
+CHUNK = 64 * 1024
+BOUNDARY = b"test-boundary"
+ORIGIN = "http://localhost:5173"
+
+
+def _build_app(service: FakePredictorService) -> FastAPI:
+ app = FastAPI()
+ app.state.backend_settings = BackendSettings()
+ app.state.predictor_service = service
+ # Same order as create_app: the cap innermost, then CORS, then request context.
+ app.add_middleware(BodySizeLimitMiddleware, max_upload_bytes=service.max_upload_bytes)
+ app.add_middleware(
+ CORSMiddleware,
+ allow_origins=[ORIGIN],
+ allow_methods=["GET", "POST", "OPTIONS"],
+ allow_headers=["*"],
+ allow_credentials=False,
+ )
+ app.add_middleware(RequestContextMiddleware)
+ app.include_router(router)
+ return app
+
+
+def _multipart(image: bytes) -> bytes:
+ return (
+ b"--" + BOUNDARY + b"\r\n"
+ b'Content-Disposition: form-data; name="image"; filename="a.jpg"\r\n'
+ b"Content-Type: image/jpeg\r\n\r\n" + image + b"\r\n--" + BOUNDARY + b"--\r\n"
+ )
+
+
+def _post(
+ app: FastAPI,
+ body: bytes,
+ *,
+ declare_length: bool,
+ after: Callable[[], None] | None = None,
+) -> dict[str, Any]:
+ """POST ``body`` to ``/v1/captions``; return the status, JSON, headers and bytes read.
+
+ ``after`` runs once the response is sent, inside the same event loop.
+ """
+ chunks = [body[i : i + CHUNK] for i in range(0, len(body), CHUNK)]
+ result: dict[str, Any] = {"read": 0, "body": b""}
+ next_chunk = 0
+
+ async def receive() -> Message:
+ nonlocal next_chunk
+ if next_chunk == len(chunks):
+ await anyio.sleep_forever() # a live connection with nothing more to send
+ chunk = chunks[next_chunk]
+ next_chunk += 1
+ result["read"] += len(chunk)
+ return {"type": "http.request", "body": chunk, "more_body": next_chunk < len(chunks)}
+
+ async def send(message: Message) -> None:
+ if message["type"] == "http.response.start":
+ result["status"] = message["status"]
+ result["headers"] = {k.decode(): v.decode() for k, v in message["headers"]}
+ elif message["type"] == "http.response.body":
+ result["body"] += message.get("body", b"")
+
+ headers = [
+ (b"content-type", b"multipart/form-data; boundary=" + BOUNDARY),
+ (b"origin", ORIGIN.encode()),
+ ]
+ if declare_length:
+ headers.append((b"content-length", str(len(body)).encode()))
+ scope = {
+ "type": "http",
+ "asgi": {"version": "3.0"},
+ "http_version": "1.1",
+ "method": "POST",
+ "scheme": "http",
+ "path": "/v1/captions",
+ "raw_path": b"/v1/captions",
+ "query_string": b"",
+ "root_path": "",
+ "headers": headers,
+ "client": ("127.0.0.1", 50000),
+ "server": ("testserver", 80),
+ }
+
+ async def run() -> None:
+ with anyio.fail_after(10):
+ await app(scope, receive, send)
+ if after is not None:
+ after()
+
+ anyio.run(run)
+ result["json"] = json.loads(result["body"])
+ return result
+
+
+def test_declared_oversize_body_is_refused_before_it_is_read() -> None:
+ service = FakePredictorService()
+ body = _multipart(b"x" * (service.max_upload_bytes + 2 * MULTIPART_OVERHEAD_BYTES))
+
+ result = _post(_build_app(service), body, declare_length=True)
+
+ assert result["status"] == 413
+ assert result["json"] == {
+ "detail": f"Image exceeds the {service.max_upload_bytes}-byte upload limit."
+ }
+ assert result["headers"].get(REQUEST_ID_HEADER)
+ assert result["headers"].get("access-control-allow-origin") == ORIGIN
+ assert result["read"] == 0
+ assert service.calls == []
+
+
+def test_undeclared_oversize_body_stops_at_the_cap() -> None:
+ service = FakePredictorService()
+ cap = service.max_upload_bytes + MULTIPART_OVERHEAD_BYTES
+ body = _multipart(b"x" * (cap * 4))
+
+ result = _post(_build_app(service), body, declare_length=False)
+
+ assert result["status"] == 413
+ assert "limit" in result["json"]["detail"]
+ assert result["read"] <= cap + CHUNK
+ assert service.calls == []
+
+
+@pytest.mark.parametrize(("extra_bytes", "status"), [(0, 200), (1, 413)])
+def test_body_under_the_cap_reaches_the_route(extra_bytes: int, status: int) -> None:
+ # Under the cap the middleware is transparent: the route's exact limit decides.
+ service = FakePredictorService()
+ image = b"x" * (service.max_upload_bytes + extra_bytes)
+ body = _multipart(image)
+
+ result = _post(_build_app(service), body, declare_length=True)
+
+ assert result["status"] == status
+ assert result["read"] == len(body)
+ if status == 200:
+ assert service.calls == [image]
+ else:
+ # The route's 413 and the middleware's 413 read the same.
+ assert result["json"] == {
+ "detail": f"Image exceeds the {service.max_upload_bytes}-byte upload limit."
+ }
+ assert service.calls == []
+
+
+def test_refused_upload_leaves_no_temp_file_open(monkeypatch: pytest.MonkeyPatch) -> None:
+ # A file part past 1 MiB is spooled to disk. Starlette doesn't close it when the cap
+ # interrupts the parse, so it must be released as soon as the request ends. anyio
+ # before 4.14.2 kept it referenced from an idle worker thread.
+ spooled: weakref.WeakSet[tempfile.SpooledTemporaryFile[bytes]] = weakref.WeakSet()
+ rollovers: list[int] = []
+ original_init = tempfile.SpooledTemporaryFile.__init__
+ original_rollover = tempfile.SpooledTemporaryFile.rollover
+
+ def tracking_init(
+ self: tempfile.SpooledTemporaryFile[bytes], *args: Any, **kwargs: Any
+ ) -> None:
+ original_init(self, *args, **kwargs)
+ spooled.add(self)
+
+ def tracking_rollover(self: tempfile.SpooledTemporaryFile[bytes]) -> None:
+ rollovers.append(1)
+ original_rollover(self)
+
+ monkeypatch.setattr(tempfile.SpooledTemporaryFile, "__init__", tracking_init)
+ monkeypatch.setattr(tempfile.SpooledTemporaryFile, "rollover", tracking_rollover)
+ service = FakePredictorService(max_upload_bytes=2 * 1024 * 1024)
+ body = _multipart(b"x" * (service.max_upload_bytes * 2))
+ still_open: list[int] = []
+
+ result = _post(
+ _build_app(service),
+ body,
+ declare_length=False,
+ after=lambda: still_open.append(sum(not f.closed for f in spooled)),
+ )
+
+ assert result["status"] == 413
+ assert rollovers, "the file part never reached disk, so this test proves nothing"
+ assert still_open == [0]
diff --git a/backend/app/tests/test_captions.py b/backend/app/tests/test_captions.py
new file mode 100644
index 0000000000000000000000000000000000000000..de7e9b77e5cb672646584a54ce3b7965e619e71b
--- /dev/null
+++ b/backend/app/tests/test_captions.py
@@ -0,0 +1,231 @@
+"""Tests for ``POST /v1/captions``.
+
+Covers the route's status-code contract end-to-end:
+
+* 200 — happy path, typed ``CaptionResponse`` body
+* 400 — empty file upload
+* 413 — payload above ``max_upload_bytes``, or image dimensions above the limits
+* 415 — disallowed content type
+* 422 — bytes that the predictor cannot decode (synthetic, or no readable image header)
+* 503 — predictor not yet loaded
+"""
+
+from __future__ import annotations
+
+import pytest
+from fastapi.testclient import TestClient
+from starlette.datastructures import UploadFile
+
+from app.tests.conftest import FakePredictorService
+from app.tests.image_bytes import encode, png_header
+
+
+def _image_field(payload: bytes, content_type: str = "image/jpeg", name: str = "a.jpg"):
+ return {"image": (name, payload, content_type)}
+
+
+def test_captions_happy_path_returns_typed_response(
+ client: TestClient, fake_service: FakePredictorService
+) -> None:
+ response = client.post("/v1/captions", files=_image_field(b"\xff\xd8stub"))
+ assert response.status_code == 200
+
+ body = response.json()
+ assert body["caption"] == "a test caption"
+ assert body["model_version"] == "test-v0"
+ assert body["decode_strategy"] == "greedy"
+ assert body["latency_ms"] == 1.23
+ assert body["request_id"]
+
+ # Service actually received the upload payload.
+ assert fake_service.calls == [b"\xff\xd8stub"]
+
+
+def test_captions_request_id_matches_response_header(client: TestClient) -> None:
+ response = client.post(
+ "/v1/captions",
+ files=_image_field(b"\xff\xd8stub"),
+ headers={"x-request-id": "trace-123"},
+ )
+ assert response.status_code == 200
+ assert response.headers.get("x-request-id") == "trace-123"
+ assert response.json()["request_id"] == "trace-123"
+
+
+def test_captions_rejects_unsupported_content_type(client: TestClient) -> None:
+ response = client.post(
+ "/v1/captions",
+ files=_image_field(b"hello", content_type="text/plain", name="a.txt"),
+ )
+ assert response.status_code == 415
+ assert "Unsupported content type" in response.json()["detail"]
+
+
+def test_captions_rejects_webp_before_reading_it(
+ client: TestClient, fake_service: FakePredictorService
+) -> None:
+ """TF 2.15 can't decode WebP, so it's refused up front instead of failing as a 422."""
+ response = client.post(
+ "/v1/captions",
+ files=_image_field(
+ b"RIFF\x1a\x00\x00\x00WEBPVP8 ", content_type="image/webp", name="a.webp"
+ ),
+ )
+ assert response.status_code == 415
+ assert "Unsupported content type" in response.json()["detail"]
+ assert fake_service.calls == []
+
+
+def test_captions_without_a_strategy_field_still_decodes_greedily(
+ client: TestClient, fake_service: FakePredictorService
+) -> None:
+ """Clients that don't send the field get exactly the old behaviour (TASK-034)."""
+ response = client.post("/v1/captions", files=_image_field(b"\xff\xd8stub"))
+ assert response.status_code == 200
+ assert response.json()["decode_strategy"] == "greedy"
+ assert fake_service.strategies == [None]
+
+
+@pytest.mark.parametrize("strategy", ["greedy", "beam"])
+def test_captions_passes_the_requested_strategy_through(
+ client: TestClient, fake_service: FakePredictorService, strategy: str
+) -> None:
+ response = client.post(
+ "/v1/captions",
+ files=_image_field(b"\xff\xd8stub"),
+ data={"decode_strategy": strategy},
+ )
+ assert response.status_code == 200
+ assert response.json()["decode_strategy"] == strategy
+ assert fake_service.strategies == [strategy]
+ assert fake_service.calls == [b"\xff\xd8stub"]
+
+
+def test_captions_treats_an_empty_strategy_field_as_omitted(
+ client: TestClient, fake_service: FakePredictorService
+) -> None:
+ """An empty form value is what a blank HTML control sends; it means the default."""
+ response = client.post(
+ "/v1/captions", files=_image_field(b"\xff\xd8stub"), data={"decode_strategy": ""}
+ )
+ assert response.status_code == 200
+ assert response.json()["decode_strategy"] == "greedy"
+ assert fake_service.strategies == [None]
+
+
+@pytest.mark.parametrize("strategy", ["sampling", "BEAM", "greedy "])
+def test_captions_rejects_an_unknown_strategy_before_reading_the_image(
+ client: TestClient, fake_service: FakePredictorService, strategy: str
+) -> None:
+ response = client.post(
+ "/v1/captions",
+ files=_image_field(b"\xff\xd8stub"),
+ data={"decode_strategy": strategy},
+ )
+ assert response.status_code == 422
+ detail = response.json()["detail"]
+ assert detail.startswith(f"Unsupported decode_strategy: {strategy!r}.")
+ assert "['greedy', 'beam']" in detail
+ assert fake_service.calls == []
+
+
+def test_captions_rejects_empty_upload(client: TestClient) -> None:
+ response = client.post("/v1/captions", files=_image_field(b""))
+ assert response.status_code == 400
+ assert "Empty" in response.json()["detail"]
+
+
+def test_captions_rejects_oversize_upload(client: TestClient) -> None:
+ # Fake service.max_upload_bytes = 1024
+ response = client.post("/v1/captions", files=_image_field(b"x" * 2048))
+ assert response.status_code == 413
+ assert "limit" in response.json()["detail"].lower()
+
+
+def test_captions_oversize_upload_reads_at_most_limit_plus_one(
+ client: TestClient,
+ fake_service: FakePredictorService,
+ monkeypatch: pytest.MonkeyPatch,
+) -> None:
+ # TASK-006: an oversized upload must not be pulled into memory in full.
+ limit = fake_service.max_upload_bytes
+ reads: list[tuple[int, int]] = [] # (requested size, bytes returned)
+ original_read = UploadFile.read
+
+ async def spy_read(self: UploadFile, size: int = -1) -> bytes:
+ data = await original_read(self, size)
+ reads.append((size, len(data)))
+ return data
+
+ monkeypatch.setattr(UploadFile, "read", spy_read)
+
+ response = client.post("/v1/captions", files=_image_field(b"x" * (limit * 10)))
+
+ assert response.status_code == 413
+ assert reads, "route never read the upload"
+ assert all(size >= 0 for size, _ in reads), f"unbounded read() call: {reads}"
+ assert sum(n for _, n in reads) <= limit + 1
+ assert fake_service.calls == []
+
+
+def test_captions_accepts_upload_exactly_at_limit(
+ client: TestClient, fake_service: FakePredictorService
+) -> None:
+ payload = b"x" * fake_service.max_upload_bytes
+ response = client.post("/v1/captions", files=_image_field(payload))
+ assert response.status_code == 200
+ assert fake_service.calls == [payload]
+
+
+def test_captions_returns_422_on_decode_failure(build_client) -> None:
+ bad_service = FakePredictorService(raise_decode_error=True)
+ with build_client(bad_service) as test_client:
+ response = test_client.post("/v1/captions", files=_image_field(b"\xff\xd8junk"))
+ assert response.status_code == 422
+ assert "synthetic decode failure" in response.json()["detail"]
+
+
+@pytest.mark.parametrize(("fmt", "content_type"), [("JPEG", "image/jpeg"), ("PNG", "image/png")])
+def test_captions_accepts_a_real_image_within_the_dimension_limits(
+ build_client, fmt: str, content_type: str
+) -> None:
+ service = FakePredictorService(check_dimensions=True, max_upload_bytes=64 * 1024)
+ payload = encode(fmt)
+ with build_client(service) as test_client:
+ response = test_client.post("/v1/captions", files=_image_field(payload, content_type))
+ assert response.status_code == 200
+ assert service.calls == [payload]
+
+
+def test_captions_returns_413_when_image_dimensions_exceed_the_limits(build_client) -> None:
+ # A 10000x5000 header in under 100 bytes: far below the byte limit.
+ service = FakePredictorService(check_dimensions=True)
+ payload = png_header(10_000, 5_000)
+ assert len(payload) < service.max_upload_bytes
+ with build_client(service) as test_client:
+ response = test_client.post(
+ "/v1/captions", files=_image_field(payload, "image/png", "big.png")
+ )
+ assert response.status_code == 413
+ assert response.json()["detail"] == (
+ "Image dimensions exceed the limit of 16384 pixels per side "
+ "and 40,000,000 pixels in total."
+ )
+
+
+def test_captions_returns_422_for_bytes_without_an_image_header(build_client) -> None:
+ service = FakePredictorService(check_dimensions=True)
+ with build_client(service) as test_client:
+ response = test_client.post("/v1/captions", files=_image_field(b"\xff\xd8junk"))
+ assert response.status_code == 422
+ assert response.json()["detail"] == (
+ "Could not decode image bytes: expected a JPEG, PNG or BMP image."
+ )
+
+
+def test_captions_returns_503_when_predictor_not_loaded(
+ client_without_service: TestClient,
+) -> None:
+ response = client_without_service.post("/v1/captions", files=_image_field(b"\xff\xd8stub"))
+ assert response.status_code == 503
+ assert "not ready" in response.json()["detail"].lower()
diff --git a/backend/app/tests/test_health.py b/backend/app/tests/test_health.py
new file mode 100644
index 0000000000000000000000000000000000000000..df6ff050bba8b771d7ce4b2e5767a21960c9e3c6
--- /dev/null
+++ b/backend/app/tests/test_health.py
@@ -0,0 +1,56 @@
+"""Tests for ``GET /healthz``.
+
+The route reports liveness + readiness in the response body and always
+returns 200; readiness is conveyed by ``model_loaded``.
+"""
+
+from __future__ import annotations
+
+from fastapi.testclient import TestClient
+
+from app.tests.conftest import FakePredictorService
+
+
+def test_healthz_reports_ready_when_service_present(client: TestClient) -> None:
+ response = client.get("/healthz")
+ assert response.status_code == 200
+
+ body = response.json()
+ assert body["status"] == "ok"
+ assert body["model_loaded"] is True
+ assert body["model_version"] == "test-v0"
+ assert body["api_version"]
+ assert "timestamp" in body
+
+
+def test_healthz_reports_loading_when_service_missing(
+ client_without_service: TestClient,
+) -> None:
+ response = client_without_service.get("/healthz")
+ assert response.status_code == 200
+
+ body = response.json()
+ assert body["status"] == "loading"
+ assert body["model_loaded"] is False
+
+
+def test_healthz_echoes_request_id_header(client: TestClient) -> None:
+ response = client.get("/healthz", headers={"x-request-id": "deadbeef"})
+ assert response.status_code == 200
+ assert response.headers.get("x-request-id") == "deadbeef"
+
+
+def test_healthz_generates_request_id_when_absent(client: TestClient) -> None:
+ response = client.get("/healthz")
+ assert response.status_code == 200
+ rid = response.headers.get("x-request-id")
+ assert rid and len(rid) >= 16
+
+
+def test_healthz_uses_overridden_model_version(
+ build_client,
+) -> None:
+ service = FakePredictorService(model_version="v9.9.9")
+ with build_client(service) as test_client:
+ body = test_client.get("/healthz").json()
+ assert body["model_version"] == "v9.9.9"
diff --git a/backend/app/tests/test_image_guard.py b/backend/app/tests/test_image_guard.py
new file mode 100644
index 0000000000000000000000000000000000000000..592e10a289318f7d16812a89ed907cc7ec243d1c
--- /dev/null
+++ b/backend/app/tests/test_image_guard.py
@@ -0,0 +1,158 @@
+"""Tests for the upload dimension guard in ``app.utils.image``.
+
+``check_image_dimensions`` reads the image header and must reject an image
+over the limits before ``bytes_to_tensor`` decodes it. Oversized inputs are
+header-only bytes (``image_bytes``), so nothing large is allocated, and
+TensorFlow is never imported here.
+"""
+
+from __future__ import annotations
+
+import struct
+import sys
+
+import pytest
+
+from app.tests.image_bytes import encode, jpeg_header, png_header
+from app.utils import image as image_module
+from app.utils.image import (
+ MAX_IMAGE_PIXELS,
+ MAX_IMAGE_SIDE,
+ ImageDecodeError,
+ ImageTooLargeError,
+ bytes_to_tensor,
+ check_image_dimensions,
+)
+
+LIMIT_MESSAGE = (
+ "Image dimensions exceed the limit of 16384 pixels per side and 40,000,000 pixels in total."
+)
+
+
+def _bmp_with_width(width: int) -> bytes:
+ data = bytearray(encode("BMP"))
+ data[18:22] = struct.pack(" bytes:
+ data = bytearray(png_header(32, 24))
+ data[29] ^= 0xFF # first byte of the IHDR checksum
+ return bytes(data)
+
+
+@pytest.mark.parametrize("fmt", ["JPEG", "PNG", "BMP"])
+def test_accepts_a_small_image(fmt: str) -> None:
+ assert check_image_dimensions(encode(fmt, size=(32, 24))) == (32, 24)
+
+
+@pytest.mark.parametrize("header", [png_header, jpeg_header])
+def test_accepts_dimensions_exactly_at_the_limits(header) -> None:
+ assert MAX_IMAGE_PIXELS == 8_000 * 5_000
+ assert check_image_dimensions(header(8_000, 5_000)) == (8_000, 5_000)
+ assert check_image_dimensions(header(MAX_IMAGE_SIDE, 1)) == (MAX_IMAGE_SIDE, 1)
+ assert check_image_dimensions(header(1, MAX_IMAGE_SIDE)) == (1, MAX_IMAGE_SIDE)
+
+
+@pytest.mark.parametrize("header", [png_header, jpeg_header])
+def test_rejects_a_pixel_count_over_the_limit(header) -> None:
+ # Both sides are within MAX_IMAGE_SIDE; only the product is over.
+ with pytest.raises(ImageTooLargeError):
+ check_image_dimensions(header(8_000, 5_001))
+
+
+@pytest.mark.parametrize("header", [png_header, jpeg_header])
+@pytest.mark.parametrize("size", [(MAX_IMAGE_SIDE + 1, 1), (1, MAX_IMAGE_SIDE + 1)])
+def test_rejects_a_side_over_the_limit(header, size: tuple[int, int]) -> None:
+ with pytest.raises(ImageTooLargeError):
+ check_image_dimensions(header(*size))
+
+
+def test_rejects_dimensions_past_pillows_own_bomb_ceiling() -> None:
+ # 65535 x 65535 makes Image.open itself raise DecompressionBombError.
+ with pytest.raises(ImageTooLargeError):
+ check_image_dimensions(png_header(65_535, 65_535))
+
+
+def test_limit_message_is_concise_and_names_only_the_limits() -> None:
+ with pytest.raises(ImageTooLargeError) as info:
+ check_image_dimensions(png_header(10_000, 5_000))
+ assert str(info.value) == LIMIT_MESSAGE
+
+
+def test_honours_explicit_limits() -> None:
+ small = encode("PNG", size=(32, 24))
+ with pytest.raises(ImageTooLargeError):
+ check_image_dimensions(small, max_side=31)
+ with pytest.raises(ImageTooLargeError):
+ check_image_dimensions(small, max_pixels=32 * 24 - 1)
+ assert check_image_dimensions(small, max_side=32, max_pixels=32 * 24) == (32, 24)
+
+
+@pytest.mark.parametrize(
+ ("data", "error"),
+ [
+ pytest.param(b"", ImageDecodeError, id="empty"),
+ pytest.param(b"not an image at all", ImageDecodeError, id="garbage"),
+ pytest.param(b"\xff\xd8\xff", ImageDecodeError, id="jpeg-soi-only"),
+ pytest.param(jpeg_header(32, 24)[:10], ImageDecodeError, id="jpeg-cut-in-sof"),
+ pytest.param(png_header(32, 24)[:20], ImageDecodeError, id="png-cut-in-ihdr"),
+ pytest.param(png_header(32, 24)[:33], ImageDecodeError, id="png-ends-after-ihdr"),
+ pytest.param(_png_with_bad_ihdr_crc(), ImageDecodeError, id="png-bad-ihdr-crc"),
+ pytest.param(png_header(0, 24), ImageDecodeError, id="png-zero-width"),
+ pytest.param(png_header(32, 0), ImageDecodeError, id="png-zero-height"),
+ pytest.param(jpeg_header(0, 24), ImageDecodeError, id="jpeg-zero-width"),
+ pytest.param(jpeg_header(32, 0), ImageDecodeError, id="jpeg-zero-height"),
+ # Pillow reads a BMP width as unsigned, so -32 claims about 4.3e9 pixels.
+ pytest.param(_bmp_with_width(-32), ImageTooLargeError, id="bmp-negative-width"),
+ ],
+)
+def test_malformed_or_invalid_headers_fail_with_a_client_error(data: bytes, error: type) -> None:
+ with pytest.raises(ImageDecodeError) as info:
+ check_image_dimensions(data)
+ assert type(info.value) is error
+
+
+@pytest.mark.parametrize("size", [(0, 24), (32, 0), (-1, 24)])
+def test_rejects_non_positive_dimensions_from_the_parser(
+ monkeypatch: pytest.MonkeyPatch, size: tuple[int, int]
+) -> None:
+ # Pillow already refuses these headers; the guard checks again on its own.
+ class _Parsed:
+ def __init__(self) -> None:
+ self.size = size
+
+ def __enter__(self) -> _Parsed:
+ return self
+
+ def __exit__(self, *exc_info: object) -> None:
+ return None
+
+ monkeypatch.setattr(image_module.Image, "open", lambda *args, **kwargs: _Parsed())
+ with pytest.raises(ImageDecodeError) as info:
+ check_image_dimensions(b"stub")
+ assert type(info.value) is ImageDecodeError
+
+
+@pytest.mark.parametrize("fmt", ["GIF", "WEBP", "TIFF"])
+def test_rejects_formats_outside_the_header_check(fmt: str) -> None:
+ # A GIF is decoded at its largest frame's size, which its header doesn't
+ # give, and opening a WebP allocates its canvas, so neither is parsed.
+ # TF 2.15 can't decode WebP or TIFF anyway.
+ with pytest.raises(ImageDecodeError) as info:
+ check_image_dimensions(encode(fmt))
+ assert type(info.value) is ImageDecodeError
+
+
+def test_bytes_to_tensor_checks_dimensions_before_importing_tensorflow(
+ monkeypatch: pytest.MonkeyPatch,
+) -> None:
+ # With TensorFlow unimportable, reaching the decoder raises ImportError.
+ monkeypatch.setitem(sys.modules, "tensorflow", None)
+
+ with pytest.raises(ImageTooLargeError):
+ bytes_to_tensor(png_header(10_000, 5_000))
+ with pytest.raises(ImageDecodeError):
+ bytes_to_tensor(b"not an image at all")
+ with pytest.raises(ImportError):
+ bytes_to_tensor(encode("PNG")) # within the limits: goes on to decode
diff --git a/backend/app/tests/test_inference_admission.py b/backend/app/tests/test_inference_admission.py
new file mode 100644
index 0000000000000000000000000000000000000000..eed5256a94a7c962adae0c4155e9ded2fb111efa
--- /dev/null
+++ b/backend/app/tests/test_inference_admission.py
@@ -0,0 +1,325 @@
+"""Tests for bounded inference admission (TASK-027).
+
+``PredictorService`` runs with a gated stand-in predictor: its
+``predict_tensor`` blocks a real worker thread until the test opens the gate,
+so requests genuinely overlap. Decoding runs the real TASK-026 header guard
+and skips TensorFlow. Nothing sleeps: tests wait for the worker threads' own
+signals, and ``fail_after`` only guards against a hang.
+"""
+
+from __future__ import annotations
+
+import math
+import threading
+from typing import Any, cast
+
+import anyio
+import httpx
+import pytest
+from anyio import from_thread, to_thread
+
+from app.api.routes import BUSY_DETAIL, BUSY_RETRY_AFTER_SECONDS
+from app.services import predictor_service
+from app.services.predictor_service import (
+ MAX_CONCURRENT_INFERENCES,
+ PredictorBusyError,
+ PredictorService,
+)
+from app.tests.conftest import _build_app
+from app.tests.image_bytes import encode, png_header
+from app.utils.image import ImageTooLargeError, check_image_dimensions
+
+IMAGE = encode("PNG")
+HANG_GUARD_SECONDS = 10 # reached only if a test is broken
+SLOTS = MAX_CONCURRENT_INFERENCES
+
+
+class InferenceFailure(Exception):
+ """A predictor failure that can't be mistaken for ``PredictorBusyError``."""
+
+
+class GatedPredictor:
+ """``predict_tensor`` holds its worker thread until ``open_gate()``."""
+
+ decode_strategy = "greedy"
+
+ def __init__(self) -> None:
+ self.error: Exception | None = None
+ self.running = 0
+ self.peak = 0
+ self.calls = 0
+ self.strategies: list[str | None] = []
+ self._gate = threading.Event()
+ self._lock = threading.Lock()
+ self._entered, self._entries = anyio.create_memory_object_stream[None](math.inf)
+
+ def predict_tensor(self, tensor: object, *, decode_strategy: str | None = None) -> str:
+ with self._lock:
+ self.calls += 1
+ self.strategies.append(decode_strategy)
+ self.running += 1
+ self.peak = max(self.peak, self.running)
+ try:
+ from_thread.run_sync(self._entered.send_nowait, None)
+ if not self._gate.wait(HANG_GUARD_SECONDS):
+ raise TimeoutError("the test never opened the gate")
+ if self.error is not None:
+ raise self.error
+ return "a gated caption"
+ finally:
+ with self._lock:
+ self.running -= 1
+
+ def open_gate(self) -> None:
+ self._gate.set()
+
+ def close_gate(self) -> None:
+ self._gate.clear()
+
+ async def wait_running(self, count: int) -> None:
+ """Return once ``count`` more calls have entered ``predict_tensor``."""
+ for _ in range(count):
+ await self._entries.receive()
+
+
+@pytest.fixture(autouse=True)
+def decoded(monkeypatch: pytest.MonkeyPatch) -> list[bytes]:
+ """Replace the TF decode with the real header guard plus a placeholder tensor."""
+ images: list[bytes] = []
+
+ def decode(image_bytes: bytes) -> str:
+ check_image_dimensions(image_bytes)
+ images.append(image_bytes)
+ return "tensor"
+
+ monkeypatch.setattr(predictor_service, "bytes_to_tensor", decode)
+ return images
+
+
+def _service(predictor: GatedPredictor, slots: int = SLOTS) -> PredictorService:
+ return PredictorService(
+ predictor=cast(Any, predictor),
+ model_version="test-v0",
+ max_upload_bytes=64 * 1024,
+ max_concurrent_inferences=slots,
+ )
+
+
+async def _saturate_then_release(
+ service: PredictorService, predictor: GatedPredictor, slots: int = SLOTS
+) -> list[str]:
+ """Fill every slot with a blocked request, check one more is refused, then finish them."""
+ captions: list[str] = []
+
+ async def caption() -> None:
+ text, _ = await service.caption_image_bytes(IMAGE)
+ captions.append(text)
+
+ with anyio.fail_after(HANG_GUARD_SECONDS):
+ async with anyio.create_task_group() as tg:
+ for _ in range(slots):
+ tg.start_soon(caption)
+ await predictor.wait_running(slots)
+ assert service.inferences_in_flight == slots
+ # Refused while every slot is still blocked, so it didn't wait for one.
+ with pytest.raises(PredictorBusyError):
+ await service.caption_image_bytes(IMAGE)
+ predictor.open_gate()
+ predictor.close_gate()
+ assert service.inferences_in_flight == 0
+ return captions
+
+
+def test_concurrent_requests_keep_their_own_decode_strategy() -> None:
+ """Two in-flight requests with different strategies never share a setting (TASK-034)."""
+
+ async def main() -> None:
+ predictor = GatedPredictor()
+ service = _service(predictor, slots=2)
+ results: dict[str, str] = {}
+
+ async def caption(strategy: str | None) -> None:
+ text, _ = await service.caption_image_bytes(IMAGE, decode_strategy=strategy)
+ results[str(strategy)] = text
+
+ with anyio.fail_after(HANG_GUARD_SECONDS):
+ async with anyio.create_task_group() as tg:
+ tg.start_soon(caption, "beam")
+ tg.start_soon(caption, None)
+ await predictor.wait_running(2)
+ assert predictor.running == 2
+ predictor.open_gate()
+ assert sorted(predictor.strategies, key=str) == [None, "beam"]
+ assert results == {"beam": "a gated caption", "None": "a gated caption"}
+ assert service.decode_strategy == "greedy" # the predictor's default is untouched
+
+ anyio.run(main)
+
+
+def test_rejects_a_limit_below_one() -> None:
+ with pytest.raises(ValueError, match="max_concurrent_inferences"):
+ _service(GatedPredictor(), slots=0)
+
+
+def test_a_request_is_admitted_when_a_slot_is_free() -> None:
+ async def main() -> None:
+ predictor = GatedPredictor()
+ predictor.open_gate()
+ service = _service(predictor)
+ with anyio.fail_after(HANG_GUARD_SECONDS):
+ caption, latency_ms = await service.caption_image_bytes(IMAGE)
+ assert caption == "a gated caption"
+ assert latency_ms >= 0
+ assert service.inferences_in_flight == 0
+
+ anyio.run(main)
+
+
+def test_a_request_over_capacity_is_refused_without_decoding(decoded: list[bytes]) -> None:
+ async def main() -> None:
+ predictor = GatedPredictor()
+ service = _service(predictor)
+ captions = await _saturate_then_release(service, predictor)
+ assert captions == ["a gated caption"] * SLOTS
+ assert len(decoded) == SLOTS # the refused request decoded nothing
+ assert predictor.calls == SLOTS
+ assert predictor.peak == SLOTS
+
+ anyio.run(main)
+
+
+def test_slots_are_released_after_successful_inference() -> None:
+ async def main() -> None:
+ predictor = GatedPredictor()
+ service = _service(predictor)
+ await _saturate_then_release(service, predictor)
+ # Every slot came back: a second full round is admitted the same way.
+ await _saturate_then_release(service, predictor)
+ assert predictor.calls == 2 * SLOTS
+ assert predictor.peak == SLOTS
+
+ anyio.run(main)
+
+
+def test_slot_is_released_when_inference_raises() -> None:
+ async def main() -> None:
+ predictor = GatedPredictor()
+ predictor.error = InferenceFailure("model failed")
+ predictor.open_gate()
+ service = _service(predictor)
+ with anyio.fail_after(HANG_GUARD_SECONDS), pytest.raises(InferenceFailure):
+ await service.caption_image_bytes(IMAGE)
+ assert service.inferences_in_flight == 0
+
+ predictor.error = None
+ predictor.close_gate()
+ await _saturate_then_release(service, predictor)
+
+ anyio.run(main)
+
+
+def test_slot_is_released_when_decoding_fails() -> None:
+ async def main() -> None:
+ predictor = GatedPredictor()
+ service = _service(predictor)
+ with anyio.fail_after(HANG_GUARD_SECONDS), pytest.raises(ImageTooLargeError):
+ await service.caption_image_bytes(png_header(10_000, 5_000))
+ assert service.inferences_in_flight == 0
+ assert predictor.calls == 0
+
+ await _saturate_then_release(service, predictor)
+
+ anyio.run(main)
+
+
+def test_a_cancelled_request_keeps_its_slot_until_its_thread_finishes() -> None:
+ async def main() -> None:
+ predictor = GatedPredictor()
+ service = _service(predictor, slots=1)
+ outcome: list[str] = []
+ scope = anyio.CancelScope()
+
+ async def request() -> None:
+ with scope:
+ await service.caption_image_bytes(IMAGE)
+ outcome.append("ended")
+
+ with anyio.fail_after(HANG_GUARD_SECONDS):
+ async with anyio.create_task_group() as tg:
+ tg.start_soon(request)
+ await predictor.wait_running(1)
+ scope.cancel()
+ await anyio.wait_all_tasks_blocked()
+ # Cancelled, but its thread is still running, so the slot stays taken
+ # and no second inference can start beside it.
+ assert outcome == []
+ assert predictor.running == 1
+ assert service.inferences_in_flight == 1
+ with pytest.raises(PredictorBusyError):
+ await service.caption_image_bytes(IMAGE)
+ predictor.open_gate()
+
+ # It ended only once its thread had finished. The cancellation can't stop
+ # that thread, and here it never surfaced: no checkpoint followed the wait.
+ assert outcome == ["ended"]
+ assert service.inferences_in_flight == 0
+ assert predictor.running == 0
+ assert predictor.peak == 1
+ caption, _ = await service.caption_image_bytes(IMAGE)
+ assert caption == "a gated caption"
+
+ anyio.run(main)
+
+
+def _upload(payload: bytes, content_type: str = "image/png") -> dict[str, Any]:
+ return {"image": ("a.png", payload, content_type)}
+
+
+def test_overload_is_a_fast_503_and_healthz_needs_no_worker_thread() -> None:
+ async def main() -> None:
+ predictor = GatedPredictor()
+ service = _service(predictor)
+ # Inference will hold every worker thread anyio has: a route that needed
+ # one would hang here until the hang guard fails the test.
+ to_thread.current_default_thread_limiter().total_tokens = SLOTS
+ app = _build_app(cast(Any, service))
+ # httpx types its ASGI app more narrowly than Starlette's own signature.
+ transport = httpx.ASGITransport(app=cast(Any, app))
+ responses: list[httpx.Response] = []
+
+ async with httpx.AsyncClient(transport=transport, base_url="http://test") as client:
+
+ async def post() -> None:
+ responses.append(await client.post("/v1/captions", files=_upload(IMAGE)))
+
+ with anyio.fail_after(HANG_GUARD_SECONDS):
+ async with anyio.create_task_group() as tg:
+ for _ in range(SLOTS):
+ tg.start_soon(post)
+ await predictor.wait_running(SLOTS)
+ assert to_thread.current_default_thread_limiter().available_tokens == 0
+
+ health = await client.get("/healthz")
+ assert health.status_code == 200
+ assert health.json()["status"] == "ok"
+ assert health.json()["model_loaded"] is True
+
+ busy = await client.post("/v1/captions", files=_upload(IMAGE))
+ assert busy.status_code == 503
+ assert busy.json()["detail"] == BUSY_DETAIL
+ assert busy.headers["retry-after"] == str(BUSY_RETRY_AFTER_SECONDS)
+ assert busy.headers["x-request-id"]
+
+ # Upload validation still runs before admission.
+ wrong_type = await client.post(
+ "/v1/captions", files=_upload(b"hello", "text/plain")
+ )
+ assert wrong_type.status_code == 415
+
+ predictor.open_gate()
+
+ assert [response.status_code for response in responses] == [200] * SLOTS
+ assert all(r.json()["caption"] == "a gated caption" for r in responses)
+ assert predictor.peak == SLOTS
+
+ anyio.run(main)
diff --git a/backend/app/tests/test_startup_integrity.py b/backend/app/tests/test_startup_integrity.py
new file mode 100644
index 0000000000000000000000000000000000000000..c94197509fc63b7aacfc694b9c9ac92ba9efa10f
--- /dev/null
+++ b/backend/app/tests/test_startup_integrity.py
@@ -0,0 +1,154 @@
+"""Startup never hands an unverified file to the model or tokenizer loader (TASK-029).
+
+These tests run the real ``lifespan`` and the real ``resolve_weights`` with its
+default downloader. Only ``huggingface_hub.snapshot_download`` (no network) and
+``CaptionPredictor`` (no TensorFlow) are replaced. The stand-in predictor reads
+the files the way the real one does: the vocabulary through ``read_vocabulary``,
+which ``CaptionTokenizer.load`` calls first, and the weights file's bytes.
+
+Importing ``app.main`` stays TensorFlow-free only while ``captioning.inference``
+imports TensorFlow inside functions. If that changes, move this module to
+``tests/unit`` so the backend suite stays TensorFlow-free.
+"""
+
+from __future__ import annotations
+
+import hashlib
+import json
+from pathlib import Path
+from typing import Any, ClassVar
+
+import anyio
+import huggingface_hub
+import pytest
+from fastapi import FastAPI
+
+import app.main as app_main
+from app.core.config import BackendSettings
+from app.services.weights_loader import PINNED_ARTIFACT_SHA256, ArtifactIntegrityError
+from captioning.config.schema import AppConfig
+from captioning.preprocessing.tokenizer import read_vocabulary
+
+REPO = "user/captioning-weights"
+COMMIT = "0123456789abcdef0123456789abcdef01234567"
+UNPINNED_COMMIT = "fedcba9876543210fedcba9876543210fedcba98"
+WEIGHTS = b"\x89HDF\r\n\x1a\nfake weights"
+VOCAB = ["", "[UNK]", "a", "dog", "on", "grass"]
+
+
+class RecordingPredictor:
+ """Stands in for ``CaptionPredictor``; records every file it consumes."""
+
+ consumed: ClassVar[list[str]] = []
+ vocabulary: ClassVar[list[str]] = []
+
+ @classmethod
+ def from_artifacts(
+ cls, *, weights_path: Path, tokenizer_dir: Path, config: AppConfig
+ ) -> RecordingPredictor:
+ cls.vocabulary = read_vocabulary(tokenizer_dir, config.model.vocabulary_size)
+ cls.consumed.append("vocab.json")
+ Path(weights_path).read_bytes()
+ cls.consumed.append(Path(weights_path).name)
+ return cls()
+
+ def warmup(self) -> None:
+ pass
+
+
+@pytest.fixture
+def snapshot(tmp_path: Path, monkeypatch: pytest.MonkeyPatch) -> Path:
+ """A snapshot holding the pinned bytes, served by a no-network downloader."""
+ directory = tmp_path / "snapshots" / COMMIT
+ directory.mkdir(parents=True)
+ vocab_bytes = json.dumps(VOCAB).encode()
+ (directory / "model.h5").write_bytes(WEIGHTS)
+ (directory / "vocab.json").write_bytes(vocab_bytes)
+ monkeypatch.setitem(
+ PINNED_ARTIFACT_SHA256,
+ (REPO, COMMIT),
+ {
+ "model.h5": hashlib.sha256(WEIGHTS).hexdigest(),
+ "vocab.json": hashlib.sha256(vocab_bytes).hexdigest(),
+ },
+ )
+ return directory
+
+
+@pytest.fixture
+def downloads(snapshot: Path, monkeypatch: pytest.MonkeyPatch) -> list[dict[str, Any]]:
+ calls: list[dict[str, Any]] = []
+
+ def fake_snapshot_download(**kwargs: Any) -> str:
+ calls.append(kwargs)
+ return str(snapshot)
+
+ monkeypatch.setattr(huggingface_hub, "snapshot_download", fake_snapshot_download)
+ monkeypatch.setattr(app_main, "CaptionPredictor", RecordingPredictor)
+ monkeypatch.setattr(RecordingPredictor, "consumed", [])
+ monkeypatch.setattr(RecordingPredictor, "vocabulary", [])
+ return calls
+
+
+def _start(revision: str = COMMIT) -> FastAPI:
+ """Run the lifespan's startup and shutdown; return the app as it was while serving."""
+ app = FastAPI()
+ app.state.backend_settings = BackendSettings(
+ weights_hub_repo=REPO, weights_hub_revision=revision, warmup=True
+ )
+ app.state.app_config = AppConfig()
+ app.state.predictor_service = None
+ seen: dict[str, Any] = {}
+
+ async def run() -> None:
+ async with app_main.lifespan(app):
+ seen["service"] = app.state.predictor_service
+
+ anyio.run(run)
+ app.state.seen_service = seen["service"]
+ return app
+
+
+def test_verified_files_load(downloads: list[dict[str, Any]]) -> None:
+ app = _start()
+
+ assert app.state.seen_service is not None
+ assert RecordingPredictor.vocabulary == VOCAB
+ assert RecordingPredictor.consumed == ["vocab.json", "model.h5"]
+ assert [call["allow_patterns"] for call in downloads] == [["model.h5", "vocab.json"]]
+ assert [call["revision"] for call in downloads] == [COMMIT]
+
+
+def test_a_tampered_weights_file_stops_startup_before_the_model_loads(
+ snapshot: Path, downloads: list[dict[str, Any]]
+) -> None:
+ (snapshot / "model.h5").write_bytes(WEIGHTS + b"\x00")
+
+ with pytest.raises(ArtifactIntegrityError, match="model.h5 has SHA-256"):
+ _start()
+
+ assert RecordingPredictor.consumed == []
+
+
+def test_a_tampered_vocabulary_is_never_read_even_when_it_would_validate(
+ snapshot: Path, downloads: list[dict[str, Any]]
+) -> None:
+ """Swapping two tokens keeps the list valid but shifts token ids."""
+ swapped = VOCAB[:2] + [VOCAB[3], VOCAB[2]] + VOCAB[4:]
+ (snapshot / "vocab.json").write_bytes(json.dumps(swapped).encode())
+ assert read_vocabulary(snapshot, AppConfig().model.vocabulary_size) == swapped
+
+ with pytest.raises(ArtifactIntegrityError, match="vocab.json has SHA-256"):
+ _start()
+
+ assert RecordingPredictor.consumed == []
+
+
+def test_an_unpinned_commit_stops_startup_before_any_download(
+ downloads: list[dict[str, Any]],
+) -> None:
+ with pytest.raises(ValueError, match="has no SHA-256 digests"):
+ _start(UNPINNED_COMMIT)
+
+ assert downloads == []
+ assert RecordingPredictor.consumed == []
diff --git a/backend/app/tests/test_weights_loader.py b/backend/app/tests/test_weights_loader.py
new file mode 100644
index 0000000000000000000000000000000000000000..6ec28183d474f00ea9ac979bb1ededb95316ab7d
--- /dev/null
+++ b/backend/app/tests/test_weights_loader.py
@@ -0,0 +1,400 @@
+"""Unit tests for ``app.services.weights_loader.resolve_weights``.
+
+These tests never hit the network — the downloader is injected as a stub.
+"""
+
+from __future__ import annotations
+
+import hashlib
+import json
+from pathlib import Path
+
+import pytest
+
+from app.core.config import BackendSettings
+from app.services.weights_loader import (
+ PINNED_ARTIFACT_SHA256,
+ PINNED_HUB_REVISIONS,
+ ArtifactIntegrityError,
+ pinned_sha256,
+ resolve_hub_commit,
+ resolve_weights,
+ sha256_file,
+)
+
+PRODUCTION_REPO = "apoorvrajdev/captioning-inceptionv3-transformer"
+COMMIT = "0123456789abcdef0123456789abcdef01234567"
+UNPINNED_COMMIT = "fedcba9876543210fedcba9876543210fedcba98"
+V1_COMMIT = "d917a47decc1f352e50ba4226e92ca5f00d47e9a"
+V2_COMMIT = "59d93b4babb16b0ac81eef598f3abc271a355cbf"
+
+# Distinct bytes per file, so a swapped or truncated file changes its digest.
+ARTIFACT_BYTES = {
+ "model.h5": b"\x89HDF\r\n\x1a\nfake weights",
+ "captioning.weights.h5": b"\x89HDF\r\n\x1a\nother fake weights",
+ "vocab.json": json.dumps(["", "[UNK]", "a", "dog"]).encode(),
+}
+
+
+def _sha256(data: bytes) -> str:
+ return hashlib.sha256(data).hexdigest()
+
+
+@pytest.fixture(autouse=True)
+def _pin_test_commit(monkeypatch: pytest.MonkeyPatch) -> None:
+ """Pin ``COMMIT`` of the test repo to the digests of ``ARTIFACT_BYTES``."""
+ monkeypatch.setitem(
+ PINNED_ARTIFACT_SHA256,
+ ("user/captioning-weights", COMMIT),
+ {name: _sha256(data) for name, data in ARTIFACT_BYTES.items()},
+ )
+
+
+def _snapshot(directory: Path, *names: str) -> Path:
+ """Create a fake snapshot directory holding the given files' test bytes."""
+ directory.mkdir(parents=True)
+ for name in names:
+ (directory / name).write_bytes(ARTIFACT_BYTES[name])
+ return directory
+
+
+def _flip_last_byte(path: Path) -> None:
+ data = bytearray(path.read_bytes())
+ data[-1] ^= 0x01
+ path.write_bytes(bytes(data))
+
+
+def _recording_downloader(snapshot: Path, calls: list[dict[str, object]]):
+ def fake_downloader(
+ *, repo_id: str, revision: str, cache_dir: str | None, allow_patterns: list[str]
+ ) -> str:
+ calls.append(
+ {
+ "repo_id": repo_id,
+ "revision": revision,
+ "cache_dir": cache_dir,
+ "allow_patterns": allow_patterns,
+ }
+ )
+ return str(snapshot)
+
+ return fake_downloader
+
+
+def test_resolve_weights_local_mode_returns_settings_paths_verbatim() -> None:
+ settings = BackendSettings(
+ weights_path=Path("models/v1.0.0/model.h5"),
+ tokenizer_dir=Path("models/v1.0.0"),
+ weights_hub_repo=None,
+ )
+
+ weights_path, tokenizer_dir = resolve_weights(settings, downloader=None)
+
+ assert weights_path == Path("models/v1.0.0/model.h5")
+ assert tokenizer_dir == Path("models/v1.0.0")
+
+
+def test_resolve_weights_hub_mode_calls_downloader_with_expected_args(tmp_path: Path) -> None:
+ fake_snapshot = _snapshot(tmp_path / "snapshots" / COMMIT, "model.h5", "vocab.json")
+ calls: list[dict[str, object]] = []
+
+ settings = BackendSettings(
+ weights_hub_repo="user/captioning-weights",
+ weights_hub_revision=COMMIT,
+ weights_hub_filename="model.h5",
+ weights_cache_dir=tmp_path / "cache",
+ )
+
+ weights_path, tokenizer_dir = resolve_weights(
+ settings, downloader=_recording_downloader(fake_snapshot, calls)
+ )
+
+ assert calls == [
+ {
+ "repo_id": "user/captioning-weights",
+ "revision": COMMIT,
+ "cache_dir": str(tmp_path / "cache"),
+ "allow_patterns": ["model.h5", "vocab.json"],
+ }
+ ]
+ assert weights_path == fake_snapshot / "model.h5"
+ assert tokenizer_dir == fake_snapshot
+
+
+def test_resolve_weights_hub_mode_passes_none_cache_dir_when_unset(tmp_path: Path) -> None:
+ fake_snapshot = _snapshot(tmp_path / "snap", "model.h5", "vocab.json")
+ calls: list[dict[str, object]] = []
+
+ settings = BackendSettings(
+ weights_hub_repo="user/captioning-weights",
+ weights_hub_revision=COMMIT,
+ weights_cache_dir=None,
+ )
+
+ resolve_weights(settings, downloader=_recording_downloader(fake_snapshot, calls))
+
+ assert [call["cache_dir"] for call in calls] == [None]
+
+
+def test_resolve_weights_hub_mode_honors_custom_weights_filename(tmp_path: Path) -> None:
+ fake_snapshot = _snapshot(tmp_path / "snap", "captioning.weights.h5", "vocab.json")
+ calls: list[dict[str, object]] = []
+
+ settings = BackendSettings(
+ weights_hub_repo="user/captioning-weights",
+ weights_hub_revision=COMMIT,
+ weights_hub_filename="captioning.weights.h5",
+ )
+
+ weights_path, _ = resolve_weights(
+ settings, downloader=_recording_downloader(fake_snapshot, calls)
+ )
+
+ assert weights_path == fake_snapshot / "captioning.weights.h5"
+ assert calls[0]["allow_patterns"] == ["captioning.weights.h5", "vocab.json"]
+
+
+def test_pinned_tag_downloads_its_recorded_commit_not_the_tag(tmp_path: Path) -> None:
+ """The Space's ``v2.0.0`` variable keeps working, but the tag never reaches the Hub.
+
+ The stub serves test bytes, so the real ``v2.0.0`` digests reject them
+ after the download.
+ """
+ fake_snapshot = _snapshot(tmp_path / "snap", "model.h5", "vocab.json")
+ calls: list[dict[str, object]] = []
+
+ settings = BackendSettings(weights_hub_repo=PRODUCTION_REPO, weights_hub_revision="v2.0.0")
+
+ with pytest.raises(ArtifactIntegrityError):
+ resolve_weights(settings, downloader=_recording_downloader(fake_snapshot, calls))
+
+ assert [call["revision"] for call in calls] == [V2_COMMIT]
+ assert [call["allow_patterns"] for call in calls] == [["model.h5", "vocab.json"]]
+
+
+@pytest.mark.parametrize(
+ ("repo_id", "revision"),
+ [
+ ("user/captioning-weights", "main"), # the settings default: a branch
+ (PRODUCTION_REPO, "main"),
+ (PRODUCTION_REPO, "v3.0.0"), # a tag nobody pinned
+ (PRODUCTION_REPO, "59d93b4"), # a short commit id
+ (PRODUCTION_REPO, "59D93B4BABB16B0AC81EEF598F3ABC271A355CBF"), # not the Hub's form
+ ("someone-else/captioning-weights", "v2.0.0"), # pinned only for the production repo
+ (PRODUCTION_REPO, ""),
+ ],
+)
+def test_unpinned_revisions_are_refused_before_any_download(
+ tmp_path: Path, repo_id: str, revision: str
+) -> None:
+ calls: list[dict[str, object]] = []
+ settings = BackendSettings(weights_hub_repo=repo_id, weights_hub_revision=revision)
+
+ with pytest.raises(ValueError, match="neither a full 40-character commit id nor a tag"):
+ resolve_weights(settings, downloader=_recording_downloader(tmp_path, calls))
+
+ assert calls == []
+
+
+@pytest.mark.parametrize(
+ ("present", "missing"),
+ [(["model.h5"], "vocab.json"), (["vocab.json"], "model.h5"), ([], "model.h5, vocab.json")],
+)
+def test_missing_artifacts_at_the_commit_fail_by_name(
+ tmp_path: Path, present: list[str], missing: str
+) -> None:
+ fake_snapshot = _snapshot(tmp_path / "snap", *present)
+ settings = BackendSettings(
+ weights_hub_repo="user/captioning-weights", weights_hub_revision=COMMIT
+ )
+
+ with pytest.raises(
+ FileNotFoundError,
+ match=f"Hub commit {COMMIT} of user/captioning-weights has no {missing}\\.",
+ ):
+ resolve_weights(settings, downloader=_recording_downloader(fake_snapshot, []))
+
+
+def test_every_pinned_revision_is_itself_a_valid_commit_id() -> None:
+ assert PINNED_HUB_REVISIONS
+ for (repo_id, tag), commit in PINNED_HUB_REVISIONS.items():
+ assert resolve_hub_commit(repo_id, commit) == commit
+ assert resolve_hub_commit(repo_id, tag) == commit
+
+
+# ---- SHA-256 verification (TASK-029) ---------------------------------------
+
+
+def test_sha256_file_matches_hashlib_across_chunk_boundaries(tmp_path: Path) -> None:
+ data = bytes(range(256)) * 41 # 10,496 bytes: not a multiple of the chunk size
+ path = tmp_path / "blob"
+ path.write_bytes(data)
+ (tmp_path / "empty").write_bytes(b"")
+
+ assert sha256_file(path, chunk_size=1000) == hashlib.sha256(data).hexdigest()
+ assert sha256_file(path) == hashlib.sha256(data).hexdigest()
+ assert sha256_file(tmp_path / "empty") == hashlib.sha256(b"").hexdigest()
+
+
+@pytest.mark.parametrize("tampered", ["model.h5", "vocab.json"])
+def test_a_one_byte_change_in_either_file_is_rejected_by_name(
+ tmp_path: Path, tampered: str
+) -> None:
+ fake_snapshot = _snapshot(tmp_path / "snap", "model.h5", "vocab.json")
+ _flip_last_byte(fake_snapshot / tampered)
+ intact = "vocab.json" if tampered == "model.h5" else "model.h5"
+ settings = BackendSettings(
+ weights_hub_repo="user/captioning-weights", weights_hub_revision=COMMIT
+ )
+
+ with pytest.raises(ArtifactIntegrityError) as excinfo:
+ resolve_weights(settings, downloader=_recording_downloader(fake_snapshot, []))
+
+ message = str(excinfo.value)
+ actual = _sha256((fake_snapshot / tampered).read_bytes())
+ expected = _sha256(ARTIFACT_BYTES[tampered])
+ assert f"{tampered} has SHA-256 {actual}, expected {expected}" in message
+ assert f"Hub commit {COMMIT} of user/captioning-weights failed verification" in message
+ assert "Nothing was loaded" in message
+ assert f"{intact} has SHA-256" not in message
+
+
+def test_every_mismatching_file_is_reported_not_just_the_first(tmp_path: Path) -> None:
+ fake_snapshot = _snapshot(tmp_path / "snap", "model.h5", "vocab.json")
+ _flip_last_byte(fake_snapshot / "model.h5")
+ _flip_last_byte(fake_snapshot / "vocab.json")
+ settings = BackendSettings(
+ weights_hub_repo="user/captioning-weights", weights_hub_revision=COMMIT
+ )
+
+ with pytest.raises(ArtifactIntegrityError, match="model.h5 has SHA-256 .*vocab.json has"):
+ resolve_weights(settings, downloader=_recording_downloader(fake_snapshot, []))
+
+
+def test_a_file_replaced_by_other_pinned_bytes_is_rejected(tmp_path: Path) -> None:
+ """Each file is checked against its own digest, not against any pinned digest."""
+ fake_snapshot = _snapshot(tmp_path / "snap", "model.h5", "vocab.json")
+ (fake_snapshot / "model.h5").write_bytes(ARTIFACT_BYTES["captioning.weights.h5"])
+ settings = BackendSettings(
+ weights_hub_repo="user/captioning-weights", weights_hub_revision=COMMIT
+ )
+
+ with pytest.raises(ArtifactIntegrityError, match="model.h5 has SHA-256"):
+ resolve_weights(settings, downloader=_recording_downloader(fake_snapshot, []))
+
+
+@pytest.mark.parametrize(
+ ("repo_id", "revision"),
+ [
+ ("user/captioning-weights", UNPINNED_COMMIT), # a valid commit id with no digests
+ (PRODUCTION_REPO, UNPINNED_COMMIT),
+ (PRODUCTION_REPO, COMMIT), # pinned only for the test repo
+ ("someone-else/captioning-weights", V2_COMMIT), # pinned only for the production repo
+ ],
+)
+def test_commits_without_pinned_digests_are_refused_before_any_download(
+ tmp_path: Path, repo_id: str, revision: str
+) -> None:
+ calls: list[dict[str, object]] = []
+ settings = BackendSettings(weights_hub_repo=repo_id, weights_hub_revision=revision)
+
+ with pytest.raises(ValueError, match=f"Hub commit {revision} of {repo_id} has no SHA-256"):
+ resolve_weights(settings, downloader=_recording_downloader(tmp_path, calls))
+
+ assert calls == []
+
+
+def test_a_pinned_tag_whose_commit_lost_its_digests_is_refused(
+ tmp_path: Path, monkeypatch: pytest.MonkeyPatch
+) -> None:
+ monkeypatch.delitem(PINNED_ARTIFACT_SHA256, (PRODUCTION_REPO, V2_COMMIT))
+ calls: list[dict[str, object]] = []
+ settings = BackendSettings(weights_hub_repo=PRODUCTION_REPO, weights_hub_revision="v2.0.0")
+
+ with pytest.raises(ValueError, match=f"Hub commit {V2_COMMIT} .* has no SHA-256 digests"):
+ resolve_weights(settings, downloader=_recording_downloader(tmp_path, calls))
+
+ assert calls == []
+
+
+@pytest.mark.parametrize(
+ ("entry", "match"),
+ [
+ ({"model.h5": _sha256(b"x")}, "no SHA-256 for vocab.json"),
+ ({"vocab.json": _sha256(b"x")}, "no SHA-256 for model.h5"),
+ ({}, "no SHA-256 for model.h5"),
+ ({"model.h5": _sha256(b"x").upper(), "vocab.json": _sha256(b"x")}, "malformed"),
+ ({"model.h5": _sha256(b"x")[:-1], "vocab.json": _sha256(b"x")}, "malformed"),
+ ({"model.h5": "g" * 64, "vocab.json": _sha256(b"x")}, "malformed"),
+ ({"model.h5": _sha256(b"x"), "vocab.json": ""}, "malformed"),
+ ],
+)
+def test_incomplete_or_malformed_digest_entries_are_refused_before_any_download(
+ tmp_path: Path, monkeypatch: pytest.MonkeyPatch, entry: dict[str, str], match: str
+) -> None:
+ monkeypatch.setitem(PINNED_ARTIFACT_SHA256, ("user/captioning-weights", COMMIT), entry)
+ calls: list[dict[str, object]] = []
+ settings = BackendSettings(
+ weights_hub_repo="user/captioning-weights", weights_hub_revision=COMMIT
+ )
+
+ with pytest.raises(ValueError, match=match):
+ resolve_weights(settings, downloader=_recording_downloader(tmp_path, calls))
+
+ assert calls == []
+
+
+def test_a_weights_filename_without_a_digest_is_refused_before_any_download(
+ tmp_path: Path,
+) -> None:
+ calls: list[dict[str, object]] = []
+ settings = BackendSettings(
+ weights_hub_repo="user/captioning-weights",
+ weights_hub_revision=COMMIT,
+ weights_hub_filename="model.keras",
+ )
+
+ with pytest.raises(ValueError, match="no SHA-256 for model.keras"):
+ resolve_weights(settings, downloader=_recording_downloader(tmp_path, calls))
+
+ assert calls == []
+
+
+def test_every_pinned_tag_has_well_formed_digests_for_both_served_files() -> None:
+ """The production tag and the rollback tag both stay servable."""
+ assert {tag for _, tag in PINNED_HUB_REVISIONS} >= {"v1.0.0", "v2.0.0"}
+ digests: list[str] = []
+ for (repo_id, _tag), commit in PINNED_HUB_REVISIONS.items():
+ expected = pinned_sha256(repo_id, commit, ["model.h5", "vocab.json"])
+ assert sorted(expected) == ["model.h5", "vocab.json"]
+ digests.extend(expected.values())
+ assert len(set(digests)) == len(digests) # no revision can pass for another
+
+
+def test_rollback_vocabulary_digest_matches_the_copy_committed_in_this_repo() -> None:
+ """Ties one pinned digest to bytes committed here long before the pin.
+
+ Git stores this file with LF line endings. A Windows checkout with
+ ``core.autocrlf`` writes CRLF, so that conversion is undone first.
+ """
+ committed = Path(__file__).resolve().parents[3] / "models" / "v1.0.0" / "vocab.json"
+ data = committed.read_bytes().replace(b"\r\n", b"\n")
+
+ assert _sha256(data) == PINNED_ARTIFACT_SHA256[(PRODUCTION_REPO, V1_COMMIT)]["vocab.json"]
+
+
+@pytest.mark.parametrize(("tag", "commit"), [("v1.0.0", V1_COMMIT), ("v2.0.0", V2_COMMIT)])
+def test_each_pinned_tag_is_checked_against_its_own_commit_digests(
+ tmp_path: Path, tag: str, commit: str
+) -> None:
+ fake_snapshot = _snapshot(tmp_path / "snap", "model.h5", "vocab.json")
+ settings = BackendSettings(weights_hub_repo=PRODUCTION_REPO, weights_hub_revision=tag)
+
+ with pytest.raises(ArtifactIntegrityError) as excinfo:
+ resolve_weights(settings, downloader=_recording_downloader(fake_snapshot, []))
+
+ message = str(excinfo.value)
+ own = PINNED_ARTIFACT_SHA256[(PRODUCTION_REPO, commit)]
+ assert f"Hub commit {commit} of {PRODUCTION_REPO}" in message
+ assert f"expected {own['model.h5']}" in message
+ assert f"expected {own['vocab.json']}" in message
diff --git a/backend/app/utils/__init__.py b/backend/app/utils/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..fe364ff44281b3526182584affb2d634e1c42179
--- /dev/null
+++ b/backend/app/utils/__init__.py
@@ -0,0 +1,5 @@
+"""HTTP-layer utilities (image decoding, etc.)."""
+
+from app.utils.image import ALLOWED_CONTENT_TYPES, ImageDecodeError, bytes_to_tensor
+
+__all__ = ["ALLOWED_CONTENT_TYPES", "ImageDecodeError", "bytes_to_tensor"]
diff --git a/backend/app/utils/image.py b/backend/app/utils/image.py
new file mode 100644
index 0000000000000000000000000000000000000000..e5add686e9e215534174b583b39f1e878d795193
--- /dev/null
+++ b/backend/app/utils/image.py
@@ -0,0 +1,147 @@
+"""Image-decoding utilities for the HTTP boundary.
+
+The ML package's ``inference/image_loader.py`` reads from disk; the API
+receives bytes in memory from a multipart upload. This module bridges the
+two: it decodes raw bytes and runs them through the *same*
+``preprocess_image_tensor`` the training pipeline uses, so train/serve
+parity is preserved by construction.
+
+Before anything decodes, ``check_image_dimensions`` reads the image header
+and rejects an image too large to decode safely: the compressed upload cap
+doesn't bound the decoded size.
+
+TensorFlow imports are deferred until first call to keep app import cheap
+(e.g. when running ``ruff`` or constructing the app for tests with stub
+predictors).
+"""
+
+from __future__ import annotations
+
+import io
+from typing import Any
+
+from PIL import Image
+
+# WebP isn't listed: TF 2.15's ``decode_image`` can't decode it, and serving
+# must decode through the training path, so a WebP upload could never succeed.
+ALLOWED_CONTENT_TYPES: frozenset[str] = frozenset(
+ {
+ "image/jpeg",
+ "image/jpg",
+ "image/png",
+ "image/bmp",
+ }
+)
+
+# Upload limits on decoded size, checked against the header before any decode.
+# The model only sees 299x299, so they bound memory, not caption quality.
+# Decoding allocates 3 bytes per pixel (uint8 RGB) and the Resizing layer then
+# makes a float32 copy (12 bytes per pixel), so a 40 MP image needs roughly
+# 600 MB per request. That figure is derived from the dtypes, not measured.
+# 40 MP admits 12-36 MP camera and phone photos; the 16,384 px side admits
+# panoramas while bounding per-row decoder buffers.
+MAX_IMAGE_PIXELS = 40_000_000
+MAX_IMAGE_SIDE = 16_384
+
+# Formats whose header is read. TF 2.15's decode_image also takes GIF, but it
+# sizes a GIF by its largest frame, which the header read doesn't see, so GIF
+# bytes are rejected (GIF isn't on the allow-list). WebP is never parsed:
+# Pillow's WebP open allocates the full canvas, and TF 2.15 can't decode WebP.
+_HEADER_FORMATS = ("JPEG", "PNG", "BMP")
+
+
+class ImageDecodeError(ValueError):
+ """Raised when uploaded bytes are not a recognisable image."""
+
+
+class ImageTooLargeError(ImageDecodeError):
+ """Raised when an image's dimensions exceed the upload limits.
+
+ Subclasses ``ImageDecodeError`` so a handler that only catches that class
+ still answers with a client error, never a 500.
+ """
+
+
+def check_image_dimensions(
+ image_bytes: bytes,
+ *,
+ max_side: int = MAX_IMAGE_SIDE,
+ max_pixels: int = MAX_IMAGE_PIXELS,
+) -> tuple[int, int]:
+ """Read the image header and reject an image too large to decode safely.
+
+ ``tf.io.decode_image`` allocates the full-resolution tensor from the
+ header's dimensions before it reads any pixel data, so a small file can
+ claim a huge image. ``Image.open`` parses only the header here; no pixel
+ is decoded.
+
+ Args:
+ image_bytes: Raw upload bytes.
+ max_side: Largest width or height accepted, in pixels.
+ max_pixels: Largest ``width * height`` accepted.
+
+ Returns:
+ ``(width, height)`` read from the header.
+
+ Raises:
+ ImageTooLargeError: If either side or the pixel count is over its limit.
+ ImageDecodeError: If the bytes aren't a JPEG, PNG or BMP with a
+ readable header and positive dimensions.
+ """
+ too_large = (
+ f"Image dimensions exceed the limit of {max_side} pixels per side "
+ f"and {max_pixels:,} pixels in total."
+ )
+ try:
+ with Image.open(io.BytesIO(image_bytes), formats=_HEADER_FORMATS) as image:
+ width, height = image.size
+ except Image.DecompressionBombError as exc:
+ # Pillow's own ceiling (about 179 MP) is far above max_pixels.
+ raise ImageTooLargeError(too_large) from exc
+ except Exception as exc:
+ # Pillow's header parsers raise many exception types on hostile input.
+ # Each one means the upload isn't an image this service accepts.
+ raise ImageDecodeError(
+ "Could not decode image bytes: expected a JPEG, PNG or BMP image."
+ ) from exc
+
+ if width <= 0 or height <= 0:
+ raise ImageDecodeError("Could not decode image bytes: invalid image dimensions.")
+ if width > max_side or height > max_side or width * height > max_pixels:
+ raise ImageTooLargeError(too_large)
+ return width, height
+
+
+def bytes_to_tensor(image_bytes: bytes) -> Any:
+ """Decode an in-memory image into a model-ready tensor.
+
+ Args:
+ image_bytes: Raw bytes from a multipart upload (JPEG/PNG/BMP).
+
+ Returns:
+ ``tf.Tensor`` of shape ``[299, 299, 3]``, dtype ``float32``, with
+ the InceptionV3 normalisation applied — i.e. exactly what
+ ``CaptionPredictor.predict_tensor`` expects.
+
+ Raises:
+ ImageTooLargeError: If the header dimensions exceed the limits.
+ ImageDecodeError: If the bytes can't be decoded as an image.
+ """
+ # Runs before TensorFlow is even imported: the decode below allocates the
+ # whole image as soon as it has read the header.
+ check_image_dimensions(image_bytes)
+
+ import tensorflow as tf
+
+ from captioning.preprocessing.image import preprocess_image_tensor
+
+ try:
+ decoded = tf.io.decode_image(
+ image_bytes,
+ channels=3,
+ expand_animations=False,
+ )
+ except (tf.errors.InvalidArgumentError, tf.errors.UnknownError) as exc:
+ raise ImageDecodeError(f"Could not decode image bytes: {exc}") from exc
+
+ return preprocess_image_tensor(decoded)
diff --git a/configs/base.yaml b/configs/base.yaml
new file mode 100644
index 0000000000000000000000000000000000000000..d32fdbabf34e8234890906d94df678d7f2f1b14d
--- /dev/null
+++ b/configs/base.yaml
@@ -0,0 +1,78 @@
+# =============================================================================
+# configs/base.yaml — single canonical config for training and inference.
+# -----------------------------------------------------------------------------
+# Every value here mirrors the IEEE notebook (cell 6 hyperparams + cell 21
+# layer wiring) so behaviour is identical to the published research. Override
+# any field on the CLI or via env var (CAPTIONING__TRAIN__BATCH_SIZE=32) — see
+# src/captioning/config/schema.py for the full validated schema.
+# =============================================================================
+
+data:
+ # Local path; scripts/prepare_data.py downloads COCO into this directory.
+ base_path: data/coco2017
+ annotations_filename: captions_train2017.json
+ images_subdir: train2017
+ sample_size: 120000 # Notebook: captions.sample(120000)
+ train_val_split: 0.8 # Notebook cell 11: int(len(img_keys) * 0.8)
+
+model:
+ embedding_dim: 512 # Notebook: EMBEDDING_DIM = 512
+ units: 512 # Notebook: UNITS = 512
+ max_length: 40 # Notebook: MAX_LENGTH = 40
+ vocabulary_size: 15000 # Notebook: VOCABULARY_SIZE = 15000
+ encoder_num_heads: 1 # Notebook cell 21: TransformerEncoderLayer(EMBEDDING_DIM, 1)
+ decoder_num_heads: 8 # Notebook cell 21: TransformerDecoderLayer(..., 8)
+ decoder_dropout_inner: 0.3 # Notebook cell 19: dropout_1 = Dropout(0.3)
+ decoder_dropout_outer: 0.5 # Notebook cell 19: dropout_2 = Dropout(0.5)
+ decoder_attention_dropout: 0.1 # Notebook cell 19: MultiHeadAttention(dropout=0.1)
+
+train:
+ epochs: 10 # Notebook: EPOCHS = 10
+ batch_size: 64 # Notebook: BATCH_SIZE = 64
+ buffer_size: 1000 # Notebook: BUFFER_SIZE = 1000
+ early_stopping_patience: 3 # Notebook cell 22: EarlyStopping(patience=3, ...)
+ seed: 42 # NEW: pin RNGs (notebook didn't seed; results varied)
+ learning_rate: 0.001 # Keras Adam default — what the notebook uses implicitly
+ weights_filename: model.h5 # Notebook cell 30: caption_model.save_weights('model.h5')
+
+serve:
+ max_upload_bytes: 10485760 # 10 MB — guard at the API edge
+ decode_strategy: greedy # Phase 1b: "beam"
+ # Beam settings for requests that ask for `decode_strategy=beam` (TASK-034).
+ # They are the committed evaluation's: results/stabilized-beam-w4-lp07-rp12
+ # (run with configs/train/stabilized.yaml, whose no_repeat_ngram_size is 3).
+ beam_width: 4
+ length_penalty: 0.7
+ repetition_penalty: 1.2
+ no_repeat_ngram_size: 3
+ cors_allowed_origins:
+ - http://localhost:3000
+ - http://localhost:5173
+ - http://localhost:5174
+ - http://127.0.0.1:5173
+ - http://127.0.0.1:5174
+
+# Phase 3 comparison — frozen protocol, docs/EVAL_METHODOLOGY.md § 8 (ADR-019).
+# Changing a value here is a dated protocol amendment, not a tuning knob.
+compare:
+ cnn: # § 8.1: the project's model as compared
+ model_id: inceptionv3-transformer-stabilized
+ hub_repo: apoorvrajdev/captioning-inceptionv3-transformer
+ revision: 59d93b4babb16b0ac81eef598f3abc271a355cbf # tag v2.0.0
+ baselines: # § 8.1: Hugging Face baselines, pinned commits
+ - model_id: blip-base
+ hub_repo: Salesforce/blip-image-captioning-base
+ revision: 82a37760796d32b1411fe092ab5d4e227313294b
+ - model_id: vit-gpt2
+ hub_repo: nlpconnect/vit-gpt2-image-captioning
+ revision: dc68f91c06a1ba6f15268e5b9c13ae7a7c514084
+ - model_id: git-base-coco
+ hub_repo: microsoft/git-base-coco
+ revision: a13141da42abd4a8cbf283601a8104265f537cee
+ baseline_decode: # § 8.4: passed explicitly to generate()
+ num_beams: 1
+ do_sample: false
+ max_new_tokens: 40
+ repetition_penalty: 1.0
+ no_repeat_ngram_size: 0
+ precision: float32
diff --git a/configs/train/debug.yaml b/configs/train/debug.yaml
new file mode 100644
index 0000000000000000000000000000000000000000..809f53481976b70502723004056b311e5af7211d
--- /dev/null
+++ b/configs/train/debug.yaml
@@ -0,0 +1,18 @@
+# =============================================================================
+# configs/train/debug.yaml — fast end-to-end smoke run.
+# -----------------------------------------------------------------------------
+# Used by CI to verify the training pipeline imports and steps once without
+# OOMing or producing NaNs. Loads on top of base.yaml so only the changed
+# fields need to be listed.
+#
+# python -m scripts.train --config configs/base.yaml --override configs/train/debug.yaml
+# =============================================================================
+
+data:
+ sample_size: 64 # Just enough captions to fill one batch
+
+train:
+ epochs: 1
+ batch_size: 8
+ buffer_size: 16
+ seed: 0
diff --git a/configs/train/stabilized.yaml b/configs/train/stabilized.yaml
new file mode 100644
index 0000000000000000000000000000000000000000..3112e0dc8d4c004a537ffbe07c5e274fafd9e503
--- /dev/null
+++ b/configs/train/stabilized.yaml
@@ -0,0 +1,84 @@
+# =============================================================================
+# configs/train/stabilized.yaml — first experimental run with the opt-in
+# training-stability primitives turned on.
+# -----------------------------------------------------------------------------
+# Identical to configs/base.yaml except for the four flags called out in the
+# `train:` section below. Every other field mirrors the IEEE notebook verbatim
+# so this run is comparable to the baseline at the same seed and architecture.
+#
+# Why a complete config (not a thin override)?
+# scripts/train.py only accepts --config; there is no --override merge mode
+# in the CLI (the README mentions one but it's aspirational, not implemented).
+# Duplicating the values here is the smallest correct change that keeps
+# base.yaml itself untouched — which was the explicit requirement for this
+# experiment phase.
+#
+# Usage:
+# python -m scripts.train --config configs/train/stabilized.yaml \
+# --output-dir outputs/runs/stabilized
+#
+# Compare against the baseline by training the same code twice — once with
+# configs/base.yaml, once with this file — and diffing the resulting
+# results//metrics.json files.
+# =============================================================================
+
+data:
+ base_path: data/coco2017
+ annotations_filename: captions_train2017.json
+ images_subdir: train2017
+ sample_size: 120000 # Same sample as base.yaml — comparability matters
+ train_val_split: 0.8
+
+model:
+ embedding_dim: 512
+ units: 512
+ max_length: 40
+ vocabulary_size: 15000
+ encoder_num_heads: 1
+ decoder_num_heads: 8
+ decoder_dropout_inner: 0.3
+ decoder_dropout_outer: 0.5
+ decoder_attention_dropout: 0.1
+
+train:
+ epochs: 10
+ batch_size: 64
+ buffer_size: 1000
+ early_stopping_patience: 3
+ seed: 42
+ learning_rate: 0.001
+ weights_filename: model.h5
+
+ # ---- the four flags this experiment is actually testing -------------------
+ # Label smoothing 0.1 softens the cross-entropy target so the decoder
+ # cannot collapse onto a handful of high-frequency tokens. Standard
+ # transformer captioning recipe (BLIP, ViT-GPT2, GIT all use it).
+ label_smoothing: 0.1
+
+ # Warmup + cosine decay replaces the bare constant Adam LR. Transformers
+ # trained from scratch with no warmup tend to settle into a "safe captions"
+ # basin where every output looks like "a man standing ...". Cosine decay
+ # then anneals smoothly toward min_learning_rate.
+ lr_schedule: cosine
+ warmup_steps: 500 # ~1/3 of an epoch at batch 64, sample 120k
+ cosine_decay_steps: null # null -> trainer derives from steps_per_epoch * epochs
+ min_learning_rate: 0.0
+
+ # Restore conventional behaviour: dropout OFF during validation, accuracy
+ # tracker weighted by token count. This gives a clean val_loss signal so
+ # EarlyStopping fires on a real plateau rather than on dropout noise.
+ honour_training_flag_in_test_step: true
+
+serve:
+ max_upload_bytes: 10485760
+ decode_strategy: greedy # Decode strategy is selected at evaluate time
+ beam_width: 4 # Stored defaults for `scripts.evaluate --decode-strategy beam`
+ length_penalty: 0.7
+ repetition_penalty: 1.0
+ no_repeat_ngram_size: 3
+ cors_allowed_origins:
+ - http://localhost:3000
+ - http://localhost:5173
+ - http://localhost:5174
+ - http://127.0.0.1:5173
+ - http://127.0.0.1:5174
diff --git a/models/v1.0.0/vocab.json b/models/v1.0.0/vocab.json
new file mode 100644
index 0000000000000000000000000000000000000000..f8ce58019af9a931021f6f5e79b39ebe4590ec35
--- /dev/null
+++ b/models/v1.0.0/vocab.json
@@ -0,0 +1,54 @@
+[
+ "",
+ "[UNK]",
+ "a",
+ "[start]",
+ "[end]",
+ "on",
+ "of",
+ "in",
+ "wooden",
+ "table",
+ "standing",
+ "sitting",
+ "woman",
+ "with",
+ "wave",
+ "two",
+ "tree",
+ "top",
+ "surfboard",
+ "street",
+ "stove",
+ "soccer",
+ "small",
+ "riding",
+ "refrigerator",
+ "red",
+ "plate",
+ "person",
+ "people",
+ "park",
+ "mountain",
+ "man",
+ "kitchen",
+ "kicking",
+ "holding",
+ "her",
+ "group",
+ "front",
+ "food",
+ "driving",
+ "down",
+ "dog",
+ "city",
+ "child",
+ "cat",
+ "bus",
+ "branch",
+ "birds",
+ "beach",
+ "ball",
+ "arms",
+ "and"
+]
diff --git a/pyproject.toml b/pyproject.toml
new file mode 100644
index 0000000000000000000000000000000000000000..b3a9c8eb9b44ce09257fb0b30efc63dd52ad3beb
--- /dev/null
+++ b/pyproject.toml
@@ -0,0 +1,248 @@
+# =============================================================================
+# pyproject.toml — single source of truth for the `captioning` Python package
+# -----------------------------------------------------------------------------
+# This file follows PEP 621 (project metadata) and PEP 517/518 (build system).
+# It replaces a scattered mix of setup.py + requirements.txt + setup.cfg with
+# one canonical config. `pip install -e .` installs the package from `src/`.
+#
+# Why src/ layout? It prevents accidental imports of the package from the
+# repo root during testing — every test exercises the *installed* package,
+# the way users will actually import it. This is the layout used by the
+# Python Packaging Authority's example projects and recommended by pytest.
+# =============================================================================
+
+[build-system]
+requires = ["setuptools>=68", "wheel"]
+build-backend = "setuptools.build_meta"
+
+# -----------------------------------------------------------------------------
+# Project metadata — what `pip show captioning` will display.
+# -----------------------------------------------------------------------------
+[project]
+name = "captioning"
+version = "0.1.0"
+description = "IEEE-published CNN+Transformer image captioning, restructured into a production-grade multimodal AI platform."
+readme = "README.md"
+requires-python = ">=3.10,<3.13"
+license = { text = "MIT" }
+authors = [
+ { name = "Apoorv Raj" },
+]
+keywords = [
+ "image-captioning",
+ "multimodal",
+ "transformer",
+ "computer-vision",
+ "tensorflow",
+ "fastapi",
+]
+classifiers = [
+ "Development Status :: 3 - Alpha",
+ "Intended Audience :: Developers",
+ "Intended Audience :: Science/Research",
+ "License :: OSI Approved :: MIT License",
+ "Programming Language :: Python :: 3",
+ "Programming Language :: Python :: 3.10",
+ "Programming Language :: Python :: 3.11",
+ "Programming Language :: Python :: 3.12",
+ "Topic :: Scientific/Engineering :: Artificial Intelligence",
+]
+
+# -----------------------------------------------------------------------------
+# Runtime dependencies for the core ML library + FastAPI backend.
+# Pinned hard. Floating versions across TF + transformers + torch is the most
+# common source of silent BLEU drift between training runs and deployments.
+#
+# - tensorflow-cpu (NOT tensorflow): saves ~600 MB and removes the CUDA driver
+# dependency. We are deploying to CPU-only HuggingFace Spaces. If you ever
+# train on a GPU box, install `tensorflow==2.15.0` in that environment only.
+# - 2.15.0 specifically: TF 2.16 swapped to Keras 3 by default and broke the
+# `tf.keras.layers.TextVectorization` saving behaviour the IEEE notebook
+# relies on. Stay on 2.15 for v1; upgrade is a deliberate Phase-5+ task.
+# - pydantic 2.x: required by FastAPI >= 0.100. Faster and stricter than v1.
+# -----------------------------------------------------------------------------
+dependencies = [
+ "tensorflow-cpu==2.15.0",
+ "numpy>=1.26,<2.0", # NumPy 2.0 broke TF 2.15 binary compat
+ "pandas>=2.1,<3.0",
+ "pillow>=12.3,<13.0", # upload header checks on the serving path; [hf] image loading
+ "pyyaml>=6.0,<7.0",
+ "pydantic>=2.7,<3.0",
+ "pydantic-settings>=2.3,<3.0",
+ "fastapi>=0.133,<1.0",
+ "starlette>=1.3.1,<2.0", # FastAPI's own floor (0.40) admits vulnerable releases
+ "uvicorn[standard]>=0.30,<1.0",
+ "python-multipart>=0.0.31", # FastAPI multipart form data (image upload)
+ "huggingface-hub>=0.23,<1.0", # Pulls weights from HF Hub at startup
+ "structlog>=24.1,<25.0", # Structured JSON logs in prod, pretty in dev
+ "anyio>=4.14.2,<5.0", # Thread-pool offload for sync TF inference
+ "tqdm>=4.66,<5.0",
+ "click>=8.1,<9.0", # CLI for scripts/
+]
+
+# -----------------------------------------------------------------------------
+# Optional dependency groups — installed via `pip install ".[dev,eval]"`.
+# Splitting these keeps the production Docker image small (Phase 1 backend
+# image is ~1.1 GB; adding `hf` extras takes it to ~2.3 GB which is the
+# Phase 3 comparison image).
+# -----------------------------------------------------------------------------
+[project.optional-dependencies]
+
+# Tier-1 multimodal upgrade: BLIP, ViT-GPT2, GIT models from HuggingFace.
+# torch CPU is large (~700 MB); only install when serving the comparison demo.
+hf = [
+ "transformers==4.41.2",
+ "torch==2.3.0",
+ "sentencepiece>=0.2.0",
+ "accelerate>=0.30,<1.0",
+]
+
+# Evaluation metrics. Pulled separately because pycocoevalcap drags Java
+# dependencies (METEOR), which we don't want in the serving image.
+eval = [
+ "sacrebleu>=2.4,<3.0",
+ "nltk>=3.8,<4.0",
+ "rouge-score>=0.1.2",
+ "pycocoevalcap>=1.2",
+ "matplotlib>=3.8,<4.0",
+]
+
+# Experiment tracking. Local SQLite by default; points at DagsHub in prod.
+mlflow = [
+ "mlflow>=2.13,<3.0",
+]
+
+# Developer tooling: lint, type-check, test. Never deployed.
+dev = [
+ "ruff>=0.5,<1.0",
+ "mypy>=1.10,<2.0",
+ "pytest>=8.2,<9.0",
+ "pytest-cov>=5.0,<6.0",
+ "pytest-asyncio>=0.23,<1.0",
+ "httpx>=0.27,<1.0", # FastAPI TestClient backend
+ "pre-commit>=3.7,<4.0",
+ "nbstripout>=0.7,<1.0",
+ "types-PyYAML",
+ "types-requests",
+ "pandas-stubs>=2.2,<3.0",
+]
+
+# -----------------------------------------------------------------------------
+# Where pip should install the package from (the `src/` layout).
+# -----------------------------------------------------------------------------
+[tool.setuptools.packages.find]
+where = ["src"]
+include = ["captioning*"]
+
+[tool.setuptools.package-data]
+"captioning" = ["py.typed"] # PEP 561: ship type hints with the package
+
+# =============================================================================
+# Tooling configuration — co-located so a single file owns project policy.
+# =============================================================================
+
+# ---- Ruff: linter + formatter (replaces black + isort + flake8) -------------
+# We prefer Ruff because it runs ~100x faster and is the de-facto modern
+# default in the Python ecosystem. One tool, one config, one cache.
+[tool.ruff]
+line-length = 100
+target-version = "py310"
+src = ["src", "backend", "scripts", "tests"]
+extend-exclude = [
+ "notebooks", # Notebooks have their own conventions
+ "outputs",
+ "mlruns",
+ "frontend",
+]
+
+[tool.ruff.lint]
+# Curated rule set — pragmatic defaults, not the full strict catalogue.
+select = [
+ "E", # pycodestyle errors
+ "W", # pycodestyle warnings
+ "F", # pyflakes
+ "I", # isort import sorting
+ "B", # flake8-bugbear (likely bugs)
+ "UP", # pyupgrade (modern syntax)
+ "SIM", # flake8-simplify
+ "RET", # flake8-return
+ "PTH", # flake8-use-pathlib (prefer pathlib over os.path)
+ "RUF", # Ruff's own rules
+]
+ignore = [
+ "E501", # line length — formatter handles it; lint warnings are noise
+ "B008", # function call in default arg (FastAPI's Depends() pattern)
+]
+
+[tool.ruff.lint.per-file-ignores]
+"tests/**" = ["B011"] # asserts in tests are fine
+"scripts/**" = ["T201"] # print() in CLI scripts is fine
+
+[tool.ruff.format]
+quote-style = "double"
+indent-style = "space"
+docstring-code-format = true
+
+# ---- Mypy: static type checker -----------------------------------------------
+# We only enforce types on our own code; third-party untyped libs are tolerated.
+[tool.mypy]
+python_version = "3.10"
+strict = false # Start lenient; tighten as types stabilise
+warn_unused_configs = true
+warn_redundant_casts = true
+warn_unused_ignores = true
+warn_no_return = true
+no_implicit_optional = true
+files = ["src/captioning", "backend/app", "scripts"]
+mypy_path = ["src", "backend"]
+explicit_package_bases = true
+namespace_packages = true
+
+[[tool.mypy.overrides]]
+module = [
+ "tensorflow.*",
+ "transformers.*",
+ "huggingface_hub.*",
+ "PIL.*",
+ "nltk.*",
+ "sacrebleu.*",
+ "rouge_score.*",
+ "pycocoevalcap.*",
+]
+ignore_missing_imports = true
+
+# ---- Pytest -------------------------------------------------------------------
+[tool.pytest.ini_options]
+minversion = "8.0"
+testpaths = ["tests", "backend/app/tests"]
+pythonpath = ["backend"] # Lets `from app.* import ...` resolve in tests
+addopts = [
+ "-ra", # Show short summary for non-passing tests
+ "--strict-markers",
+ "--strict-config",
+ "--showlocals",
+]
+markers = [
+ "slow: tests that take >10 seconds (run with -m slow)",
+ "gpu: tests requiring a GPU (skipped in CI by default)",
+]
+filterwarnings = [
+ "ignore::DeprecationWarning:tensorflow.*",
+ "ignore::FutureWarning:tensorflow.*",
+]
+
+# ---- Coverage -----------------------------------------------------------------
+[tool.coverage.run]
+branch = true
+source = ["src/captioning", "backend/app"]
+omit = ["*/tests/*", "*/__init__.py"]
+
+[tool.coverage.report]
+exclude_lines = [
+ "pragma: no cover",
+ "raise NotImplementedError",
+ "if TYPE_CHECKING:",
+ "if __name__ == .__main__.:",
+]
+show_missing = true
+skip_covered = false
diff --git a/requirements.txt b/requirements.txt
new file mode 100644
index 0000000000000000000000000000000000000000..ccdc79df2fc7956924b840ccea2ea4cd33318963
--- /dev/null
+++ b/requirements.txt
@@ -0,0 +1,51 @@
+# =============================================================================
+# requirements.txt — runtime dependencies for the FastAPI backend (slim).
+# -----------------------------------------------------------------------------
+# This file mirrors `[project.dependencies]` in pyproject.toml so that
+# Docker builds and CI can `pip install -r requirements.txt` without needing
+# the package source available.
+#
+# To regenerate from pyproject.toml later (recommended after Phase 1):
+# pip install pip-tools
+# pip-compile --extra=hf pyproject.toml -o requirements.txt
+#
+# All versions are pinned. Floating versions across TF + transformers + torch
+# is the most common silent source of BLEU drift between runs and deploys.
+# =============================================================================
+
+# ---- Core ML framework -------------------------------------------------------
+# CPU-only TF: deploy target is CPU HuggingFace Spaces. Pinned at 2.15 because
+# 2.16+ ships Keras 3 by default, which breaks the IEEE notebook's
+# `tf.keras.layers.TextVectorization` save/load semantics.
+tensorflow-cpu==2.15.0
+
+# ---- Numerics / data ---------------------------------------------------------
+# NumPy <2.0 because TF 2.15 was built against the 1.x ABI.
+numpy==1.26.4
+pandas==2.2.2
+# Serving reads upload headers with it (JPEG, PNG and BMP only) to enforce the
+# pixel limits; pixels still decode via tf.io.decode_image. The [hf] baseline
+# adapter reads images with it.
+pillow==12.3.0
+pyyaml==6.0.1
+
+# ---- Config & validation -----------------------------------------------------
+pydantic==2.7.4
+pydantic-settings==2.3.4
+
+# ---- API server --------------------------------------------------------------
+fastapi==0.133.0
+# Pinned explicitly: FastAPI's own range (starlette>=0.40.0) still admits
+# Starlette versions with known advisories.
+starlette==1.3.1
+uvicorn[standard]==0.30.1
+python-multipart==0.0.31
+
+# ---- Model artefact pull at startup ------------------------------------------
+huggingface-hub==0.23.4
+
+# ---- Logging / async / CLI ---------------------------------------------------
+structlog==24.2.0
+anyio==4.14.2
+tqdm==4.66.4
+click==8.1.7
diff --git a/src/captioning/__init__.py b/src/captioning/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..83af0fbf70ab1636f211be26d988515c44206117
--- /dev/null
+++ b/src/captioning/__init__.py
@@ -0,0 +1,23 @@
+"""Captioning — production-grade extraction of the IEEE image-captioning research.
+
+The package mirrors the IEEE notebook
+(``notebooks/01_ieee_inceptionv3_transformer.ipynb``) but separates orthogonal
+concerns into sub-packages so each piece is independently testable, composable,
+and reusable from FastAPI / scripts.
+
+Sub-package map:
+ config/ Pydantic settings + YAML loader (the project's "type system")
+ preprocessing/ Pure transforms on captions and images (no I/O, no state)
+ data/ COCO loaders, splits, tf.data pipelines (I/O + statefulness)
+ models/ Keras layers and models (CNN encoder + Transformer decoder)
+ training/ Losses, callbacks, training orchestration
+ inference/ Generation algorithms + a singleton-friendly Predictor
+ evaluation/ BLEU/CIDEr/METEOR/ROUGE (Phase 1b expands these)
+ baselines/ Phase 3 captioner interface: CNN + Hugging Face adapters
+ utils/ Cross-cutting helpers (logging, seed, hashing, paths)
+
+Public API is intentionally small. Everything else is internal and may change.
+"""
+
+__version__ = "0.1.0"
+__all__ = ["__version__"]
diff --git a/src/captioning/baselines/__init__.py b/src/captioning/baselines/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..d7f068e6943cc9847de169735a4b0039a90dbc64
--- /dev/null
+++ b/src/captioning/baselines/__init__.py
@@ -0,0 +1,24 @@
+"""Phase 3 comparison models behind one captioning interface (ADR-019).
+
+Every compared model (the project's CNN + Transformer and the pretrained
+Hugging Face baselines) captions images through :class:`Captioner`, so the
+comparison runner and the latency benchmark share one call path and one
+caption normalisation.
+
+``transformers`` and ``torch`` belong to the optional ``[hf]`` extra and are
+imported only inside :meth:`HFCaptioner.load`. Importing this package loads
+neither of them, and doesn't load TensorFlow either.
+"""
+
+from captioning.baselines.base import Captioner, CaptionerIdentity
+from captioning.baselines.cnn import CNNCaptioner
+from captioning.baselines.hf import HF_INSTALL_HINT, HFCaptioner, MissingHFDependencyError
+
+__all__ = [
+ "HF_INSTALL_HINT",
+ "CNNCaptioner",
+ "Captioner",
+ "CaptionerIdentity",
+ "HFCaptioner",
+ "MissingHFDependencyError",
+]
diff --git a/src/captioning/baselines/base.py b/src/captioning/baselines/base.py
new file mode 100644
index 0000000000000000000000000000000000000000..66ce16dc6bdade0fe455d13be094e10dc037a9e0
--- /dev/null
+++ b/src/captioning/baselines/base.py
@@ -0,0 +1,64 @@
+"""The captioner interface shared by every Phase 3 model."""
+
+from __future__ import annotations
+
+from abc import ABC, abstractmethod
+from collections.abc import Mapping, Sequence
+from dataclasses import dataclass, field
+from pathlib import Path
+from types import MappingProxyType
+
+from captioning.evaluation.tokenization import strip_sentinels
+from captioning.preprocessing.caption import preprocess_caption
+
+
+@dataclass(frozen=True)
+class CaptionerIdentity:
+ """What a run records about the model behind its captions.
+
+ Attributes:
+ model_id: The ``run_meta.json`` model id (``EVAL_METHODOLOGY.md`` § 8.1).
+ hub_repo: Hugging Face Hub repository the weights come from, if any.
+ revision: Pinned commit SHA of ``hub_repo``, if any.
+ decode_settings: The decoding parameters actually used. Read-only.
+ """
+
+ model_id: str
+ hub_repo: str | None
+ revision: str | None
+ decode_settings: Mapping[str, object] = field(default_factory=dict)
+
+ def __post_init__(self) -> None:
+ object.__setattr__(self, "decode_settings", MappingProxyType(dict(self.decode_settings)))
+
+
+class Captioner(ABC):
+ """Captions a batch of images and normalises the result.
+
+ Subclasses produce raw captions; :meth:`caption` normalises every one of
+ them through the existing training path (``preprocess_caption``, then
+ ``strip_sentinels``), so all compared models are scored on the same
+ footing (``EVAL_METHODOLOGY.md`` § 8.3).
+ """
+
+ def __init__(self, identity: CaptionerIdentity) -> None:
+ self.identity = identity
+
+ def load(self) -> None: # noqa: B027 - optional hook, a no-op by default
+ """Load model weights if they aren't loaded yet. Safe to call repeatedly."""
+
+ def caption(self, image_paths: Sequence[str | Path]) -> list[str]:
+ """Return one normalised caption per image, in input order."""
+ paths = [Path(p) for p in image_paths]
+ if not paths:
+ return []
+ raw = self._raw_captions(paths)
+ if len(raw) != len(paths):
+ raise RuntimeError(
+ f"{self.identity.model_id}: {len(raw)} captions for {len(paths)} images"
+ )
+ return [strip_sentinels(preprocess_caption(text)) for text in raw]
+
+ @abstractmethod
+ def _raw_captions(self, image_paths: list[Path]) -> list[str]:
+ """Return the model's captions for ``image_paths``, before normalisation."""
diff --git a/src/captioning/baselines/cnn.py b/src/captioning/baselines/cnn.py
new file mode 100644
index 0000000000000000000000000000000000000000..adad089d8f48b0401778ce2487df63828704ba83
--- /dev/null
+++ b/src/captioning/baselines/cnn.py
@@ -0,0 +1,101 @@
+"""The project's CNN + Transformer as a :class:`Captioner`."""
+
+from __future__ import annotations
+
+from pathlib import Path
+from typing import TYPE_CHECKING, Any, Protocol
+
+from captioning.baselines.base import Captioner, CaptionerIdentity
+from captioning.config.schema import AppConfig, ComparedModelConfig
+
+if TYPE_CHECKING:
+ from captioning.inference.predictor import DecodeStrategy
+
+
+class _ModelSettings(Protocol):
+ max_length: int
+
+
+class _PredictorConfig(Protocol):
+ @property
+ def model(self) -> _ModelSettings: ...
+
+
+class PathPredictor(Protocol):
+ """The part of ``CaptionPredictor`` the adapter relies on."""
+
+ decode_strategy: str
+ beam_width: int
+ length_penalty: float
+ repetition_penalty: float
+ no_repeat_ngram_size: int
+
+ @property
+ def config(self) -> _PredictorConfig: ...
+
+ def predict_path(self, image_path: str | Path) -> str: ...
+
+
+class CNNCaptioner(Captioner):
+ """Wraps a loaded ``CaptionPredictor`` without changing how it decodes.
+
+ Each image goes through ``predictor.predict_path``, one at a time, exactly
+ as ``scripts/evaluate.py`` does. The recorded decode settings follow
+ ``run_meta.json``: beam-only parameters are ``None`` for greedy decoding.
+ """
+
+ def __init__(self, predictor: PathPredictor, model: ComparedModelConfig) -> None:
+ beam = predictor.decode_strategy == "beam"
+ super().__init__(
+ CaptionerIdentity(
+ model_id=model.model_id,
+ hub_repo=model.hub_repo,
+ revision=model.revision,
+ decode_settings={
+ "decode_strategy": predictor.decode_strategy,
+ "beam_width": predictor.beam_width if beam else None,
+ "length_penalty": predictor.length_penalty if beam else None,
+ "repetition_penalty": predictor.repetition_penalty,
+ "no_repeat_ngram_size": predictor.no_repeat_ngram_size,
+ "max_length": predictor.config.model.max_length,
+ },
+ )
+ )
+ self._predictor = predictor
+
+ @classmethod
+ def from_artifacts(
+ cls,
+ weights_path: str | Path,
+ tokenizer_dir: str | Path,
+ config: AppConfig,
+ *,
+ decode_strategy: DecodeStrategy | None = None,
+ beam_width: int | None = None,
+ length_penalty: float | None = None,
+ repetition_penalty: float | None = None,
+ no_repeat_ngram_size: int | None = None,
+ ) -> CNNCaptioner:
+ """Load the checkpoint with ``CaptionPredictor.from_artifacts``.
+
+ Decoding arguments are passed through unchanged, so unset ones fall
+ back to ``config.serve`` just as they do for ``scripts/evaluate.py``.
+ The identity comes from ``config.compare.cnn``. TensorFlow is imported
+ here, not when this module is imported.
+ """
+ from captioning.inference.predictor import CaptionPredictor
+
+ predictor: Any = CaptionPredictor.from_artifacts(
+ weights_path,
+ tokenizer_dir,
+ config,
+ decode_strategy=decode_strategy,
+ beam_width=beam_width,
+ length_penalty=length_penalty,
+ repetition_penalty=repetition_penalty,
+ no_repeat_ngram_size=no_repeat_ngram_size,
+ )
+ return cls(predictor, config.compare.cnn)
+
+ def _raw_captions(self, image_paths: list[Path]) -> list[str]:
+ return [self._predictor.predict_path(path) for path in image_paths]
diff --git a/src/captioning/baselines/hf.py b/src/captioning/baselines/hf.py
new file mode 100644
index 0000000000000000000000000000000000000000..96bb53d39ab928fa64a07b2902162439982b453a
--- /dev/null
+++ b/src/captioning/baselines/hf.py
@@ -0,0 +1,126 @@
+"""Pretrained Hugging Face captioning baselines as a :class:`Captioner`.
+
+``torch`` and ``transformers`` (the optional ``[hf]`` extra) are imported only
+inside :meth:`HFCaptioner.load`, through ``importlib``, so importing this
+module never loads them (ADR-019).
+"""
+
+from __future__ import annotations
+
+import importlib
+from dataclasses import dataclass
+from pathlib import Path
+from typing import Any
+
+from PIL import Image
+
+from captioning.baselines.base import Captioner, CaptionerIdentity
+from captioning.config.schema import BaselineDecodeConfig, ComparedModelConfig
+
+HF_INSTALL_HINT = 'pip install -e ".[hf]"'
+
+
+class MissingHFDependencyError(ImportError):
+ """A Hugging Face baseline was used without the ``[hf]`` extra installed."""
+
+
+@dataclass(frozen=True)
+class _Loaded:
+ torch: Any
+ dtype: Any
+ image_processor: Any
+ tokenizer: Any
+ model: Any
+
+
+class HFCaptioner(Captioner):
+ """One Hugging Face image-to-text model, pinned to an exact revision.
+
+ BLIP-base, ViT-GPT2 and GIT-base-coco all load through
+ ``AutoImageProcessor``, ``AutoTokenizer`` and ``AutoModelForVision2Seq``.
+ Generation uses only the protocol's decode settings, passed explicitly to
+ ``generate()``, with no text prompt (``EVAL_METHODOLOGY.md`` § 8.4).
+
+ Construction is cheap and needs no ``[hf]`` packages. Weights load on
+ :meth:`load`, or on the first :meth:`caption` call.
+ """
+
+ def __init__(
+ self,
+ model: ComparedModelConfig,
+ decode: BaselineDecodeConfig,
+ *,
+ device: str = "cpu",
+ ) -> None:
+ super().__init__(
+ CaptionerIdentity(
+ model_id=model.model_id,
+ hub_repo=model.hub_repo,
+ revision=model.revision,
+ decode_settings=decode.model_dump(),
+ )
+ )
+ self._model = model
+ self._decode = decode
+ self._device = device
+ self._loaded: _Loaded | None = None
+
+ @property
+ def generate_kwargs(self) -> dict[str, Any]:
+ """The exact keyword arguments passed to ``model.generate()``."""
+ return {
+ "num_beams": self._decode.num_beams,
+ "do_sample": self._decode.do_sample,
+ "max_new_tokens": self._decode.max_new_tokens,
+ "repetition_penalty": self._decode.repetition_penalty,
+ "no_repeat_ngram_size": self._decode.no_repeat_ngram_size,
+ }
+
+ def load(self) -> None:
+ """Load the processor, tokenizer and model at the pinned revision.
+
+ Raises:
+ MissingHFDependencyError: If ``torch`` or ``transformers`` is not
+ installed.
+ """
+ if self._loaded is not None:
+ return
+ torch, transformers = _import_hf()
+ repo, revision = self._model.hub_repo, self._model.revision
+ dtype = getattr(torch, self._decode.precision)
+ image_processor = transformers.AutoImageProcessor.from_pretrained(repo, revision=revision)
+ tokenizer = transformers.AutoTokenizer.from_pretrained(repo, revision=revision)
+ model = transformers.AutoModelForVision2Seq.from_pretrained(
+ repo, revision=revision, torch_dtype=dtype
+ )
+ model = model.to(self._device)
+ model.eval()
+ self._loaded = _Loaded(torch, dtype, image_processor, tokenizer, model)
+
+ def _raw_captions(self, image_paths: list[Path]) -> list[str]:
+ self.load()
+ loaded = self._loaded
+ assert loaded is not None
+ images = [_open_rgb(path) for path in image_paths]
+ pixel_values = loaded.image_processor(images=images, return_tensors="pt").pixel_values
+ pixel_values = pixel_values.to(self._device, dtype=loaded.dtype)
+ with loaded.torch.inference_mode():
+ output_ids = loaded.model.generate(pixel_values=pixel_values, **self.generate_kwargs)
+ return list(loaded.tokenizer.batch_decode(output_ids, skip_special_tokens=True))
+
+
+def _import_hf() -> tuple[Any, Any]:
+ try:
+ torch = importlib.import_module("torch")
+ transformers = importlib.import_module("transformers")
+ except ImportError as exc:
+ raise MissingHFDependencyError(
+ "Hugging Face baselines need the optional [hf] extra (transformers, torch). "
+ f"Install it with: {HF_INSTALL_HINT}"
+ ) from exc
+ return torch, transformers
+
+
+def _open_rgb(path: Path) -> Image.Image:
+ with Image.open(path) as image:
+ return image.convert("RGB")
diff --git a/src/captioning/config/__init__.py b/src/captioning/config/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..27c46e2aa860a391d0980a34389f93e20debf419
--- /dev/null
+++ b/src/captioning/config/__init__.py
@@ -0,0 +1,30 @@
+"""Configuration package — Pydantic schemas and YAML loaders.
+
+Why a dedicated package? Configs are the project's *type system*. Every other
+module accepts an `AppConfig` (or a sub-config) instead of pulling globals,
+which makes them testable in isolation and trivially overridable in CI / serve.
+"""
+
+from captioning.config.loader import load_config
+from captioning.config.schema import (
+ AppConfig,
+ BaselineDecodeConfig,
+ CompareConfig,
+ ComparedModelConfig,
+ DataConfig,
+ ModelConfig,
+ ServeConfig,
+ TrainConfig,
+)
+
+__all__ = [
+ "AppConfig",
+ "BaselineDecodeConfig",
+ "CompareConfig",
+ "ComparedModelConfig",
+ "DataConfig",
+ "ModelConfig",
+ "ServeConfig",
+ "TrainConfig",
+ "load_config",
+]
diff --git a/src/captioning/config/loader.py b/src/captioning/config/loader.py
new file mode 100644
index 0000000000000000000000000000000000000000..34d3e37ebb0ee14ad7374af8a4acacac785ca787
--- /dev/null
+++ b/src/captioning/config/loader.py
@@ -0,0 +1,73 @@
+"""YAML-to-Pydantic config loader.
+
+Why this exists separately from ``schema.py``:
+ * Schema is *what* a valid config looks like; loader is *how* you build one.
+ Splitting them lets tests build an ``AppConfig`` programmatically without
+ touching disk, and lets the loader gain features (env-file resolution,
+ multi-file merging) without changing the schema.
+"""
+
+from __future__ import annotations
+
+from pathlib import Path
+from typing import Any
+
+import yaml
+from pydantic_settings import EnvSettingsSource
+
+from captioning.config.schema import AppConfig
+
+
+def load_config(path: str | Path) -> AppConfig:
+ """Load a YAML file into an ``AppConfig``, apply env overrides, and validate it.
+
+ Precedence, highest first: ``CAPTIONING__*`` environment variables, the
+ YAML file, the schema defaults. An override replaces only the field it
+ names (``CAPTIONING__SERVE__BEAM_WIDTH=4`` keeps the rest of ``serve``);
+ a list value, such as ``CAPTIONING__SERVE__CORS_ALLOWED_ORIGINS``,
+ replaces the YAML list whole.
+
+ Args:
+ path: Path to a YAML file with the structure::
+
+ data: {...}
+ model: {...}
+ train: {...}
+ serve: {...}
+
+ Returns:
+ A fully validated, immutable ``AppConfig`` instance.
+
+ Raises:
+ FileNotFoundError: If the YAML path does not exist.
+ pydantic.ValidationError: If any field fails validation.
+ pydantic_settings.sources.SettingsError: If an env value for a list or
+ section isn't valid JSON.
+ """
+ path = Path(path)
+ if not path.is_file():
+ raise FileNotFoundError(f"Config file not found: {path}")
+
+ with path.open(encoding="utf-8") as f:
+ raw: dict[str, Any] = yaml.safe_load(f) or {}
+
+ # pydantic-settings ranks constructor arguments above the environment, so
+ # ``AppConfig(**raw)`` alone would let the YAML win. Merge the env values
+ # over it first, parsed by the same source ``AppConfig`` uses.
+ env = EnvSettingsSource(AppConfig)()
+ return AppConfig(**_merge(raw, env))
+
+
+def _merge(base: dict[str, Any], override: dict[str, Any]) -> dict[str, Any]:
+ """Return ``base`` updated by ``override``, recursing into sections both set.
+
+ Any other value, lists included, is replaced whole, as pydantic-settings
+ merges its own sources.
+ """
+ merged = dict(base)
+ for key, value in override.items():
+ if isinstance(value, dict) and isinstance(merged.get(key), dict):
+ merged[key] = _merge(merged[key], value)
+ else:
+ merged[key] = value
+ return merged
diff --git a/src/captioning/config/schema.py b/src/captioning/config/schema.py
new file mode 100644
index 0000000000000000000000000000000000000000..8c4315c3e7e98ff553c6dee4f732db27fae840bb
--- /dev/null
+++ b/src/captioning/config/schema.py
@@ -0,0 +1,289 @@
+"""Typed configuration schemas (Pydantic v2 ``BaseSettings``).
+
+These classes replace the bare globals ``MAX_LENGTH``, ``BATCH_SIZE``, ... that
+the notebook holds in cell 6. The advantages of doing this:
+
+1. **Type safety** — every field has a declared type and Pydantic validates
+ it at load time. A YAML typo (``batch_size: "64"`` as a string) raises an
+ error pointing at the file and field, not a mysterious training failure
+ six steps later.
+2. **Env override** — ``CAPTIONING__TRAIN__BATCH_SIZE=32`` overrides
+ ``train.batch_size`` without editing YAML. The double underscore is the
+ nesting delimiter (configurable below). Useful for CI smoke tests.
+3. **Single source of truth** — every other module accepts a sub-config
+ (``ModelConfig``, ``TrainConfig``, ...) instead of pulling globals. That
+ makes them testable in isolation and trivially overridable in serve.
+
+The schema mirrors the IEEE notebook 1:1 — same field names where reasonable,
+same default values. Extending it (Phase 1b: warmup/cosine LR; Phase 3: model
+registry) only adds new fields, never changes the meaning of existing ones.
+"""
+
+from __future__ import annotations
+
+from pathlib import Path
+from typing import Literal
+
+from pydantic import BaseModel, ConfigDict, Field, field_validator, model_validator
+from pydantic_settings import BaseSettings, SettingsConfigDict
+
+
+class _StrictModel(BaseModel):
+ """Shared base for every sub-config — rejects unknown keys.
+
+ Pydantic's default ``extra="ignore"`` silently drops misspelled fields.
+ For configs that drive ML hyperparameters that's the worst possible
+ behaviour: a typo (``vocabularsy_size`` instead of ``vocabulary_size``)
+ silently uses the default and the model trains with the wrong value.
+ Forbidding extras turns every typo into a load-time error pointing at
+ the offending field.
+
+ Note: ``extra="forbid"`` is set on ``AppConfig`` separately because
+ ``BaseSettings`` uses ``SettingsConfigDict``, not ``ConfigDict``.
+ """
+
+ model_config = ConfigDict(extra="forbid")
+
+
+class DataConfig(_StrictModel):
+ """Where the dataset lives and how much of it to use.
+
+ Attributes:
+ base_path: Root of the COCO dataset. Mirrors the notebook's
+ ``BASE_PATH = '../input/coco-2017-dataset/coco2017'``.
+ annotations_filename: Name of the captions JSON inside ``annotations/``.
+ images_subdir: Sub-folder under ``base_path`` containing JPEGs.
+ sample_size: How many caption pairs to sample. The notebook samples
+ 120k. Set to ``-1`` to use the full set.
+ train_val_split: Fraction of *images* (not captions) used for training.
+ Splitting at the image level prevents the same image appearing in
+ both splits via different captions — a real leakage source.
+ """
+
+ base_path: Path = Path("data/coco2017")
+ annotations_filename: str = "captions_train2017.json"
+ images_subdir: str = "train2017"
+ sample_size: int = 120_000
+ train_val_split: float = 0.8
+
+ @field_validator("train_val_split")
+ @classmethod
+ def _validate_split(cls, v: float) -> float:
+ if not 0.0 < v < 1.0:
+ raise ValueError(f"train_val_split must be in (0, 1), got {v}")
+ return v
+
+
+class ModelConfig(_StrictModel):
+ """Architecture hyperparameters.
+
+ Defaults match the IEEE paper / notebook cell 6 exactly. Changing any of
+ these requires re-training and re-publishing the model card on HF Hub.
+ """
+
+ embedding_dim: int = 512
+ units: int = 512
+ max_length: int = 40
+ vocabulary_size: int = 15_000
+ encoder_num_heads: int = 1 # Notebook cell 21: TransformerEncoderLayer(EMBEDDING_DIM, 1)
+ decoder_num_heads: int = 8 # Notebook cell 21: TransformerDecoderLayer(..., 8)
+ decoder_dropout_inner: float = 0.3 # Notebook cell 19: dropout_1
+ decoder_dropout_outer: float = 0.5 # Notebook cell 19: dropout_2
+ decoder_attention_dropout: float = 0.1 # Notebook cell 19: MultiHeadAttention(dropout=0.1)
+
+
+class TrainConfig(_StrictModel):
+ """Optimisation hyperparameters.
+
+ The Phase 1 baseline mirrors the IEEE notebook: constant LR, no label
+ smoothing, dropout-active validation (a notebook quirk preserved for
+ parity). The fields below the comment line are *opt-in* training-
+ stability knobs added during the caption-quality stabilisation phase.
+ Defaults keep every existing run byte-for-byte identical to the
+ notebook; flipping the flag in YAML opts a run into the modern recipe.
+ """
+
+ epochs: int = 10
+ batch_size: int = 64
+ buffer_size: int = 1_000 # tf.data shuffle buffer
+ early_stopping_patience: int = 3
+ seed: int = 42 # NEW (not in notebook): pin RNGs for reproducibility
+ learning_rate: float = 1e-3 # Notebook uses Keras Adam default == 1e-3
+ weights_filename: str = "model.h5"
+
+ # ---- opt-in stability flags (default values preserve notebook parity) ----
+ label_smoothing: float = 0.0
+ lr_schedule: str = "constant" # "constant" | "cosine"
+ warmup_steps: int = 0
+ cosine_decay_steps: int | None = None # If None, derived from epochs * steps_per_epoch
+ min_learning_rate: float = 0.0
+ honour_training_flag_in_test_step: bool = False # parity-quirk override
+
+ @field_validator("label_smoothing")
+ @classmethod
+ def _validate_label_smoothing(cls, v: float) -> float:
+ if not 0.0 <= v < 1.0:
+ raise ValueError(f"label_smoothing must be in [0, 1), got {v}")
+ return v
+
+ @field_validator("lr_schedule")
+ @classmethod
+ def _validate_lr_schedule(cls, v: str) -> str:
+ if v not in {"constant", "cosine"}:
+ raise ValueError(f"lr_schedule must be 'constant' or 'cosine', got {v!r}")
+ return v
+
+ @field_validator("warmup_steps")
+ @classmethod
+ def _validate_warmup_steps(cls, v: int) -> int:
+ if v < 0:
+ raise ValueError(f"warmup_steps must be >= 0, got {v}")
+ return v
+
+
+class ServeConfig(_StrictModel):
+ """Settings for the FastAPI backend (Phase 2). Defined here so the schema
+ is complete and tests don't have to mock a sub-config's existence.
+
+ Decoding-related defaults are deliberately conservative: ``greedy`` stays
+ the default for byte-for-byte parity with the IEEE notebook. Switching to
+ beam at deploy time is a one-line YAML override:
+
+ serve:
+ decode_strategy: beam
+ beam_width: 4
+ length_penalty: 0.7
+ repetition_penalty: 1.1
+ no_repeat_ngram_size: 3
+ """
+
+ max_upload_bytes: int = 10 * 1024 * 1024 # 10 MB
+ decode_strategy: str = "greedy"
+ beam_width: int = 3
+ length_penalty: float = 1.0
+ repetition_penalty: float = 1.0
+ no_repeat_ngram_size: int = 0
+ cors_allowed_origins: list[str] = Field(default_factory=lambda: ["http://localhost:3000"])
+
+ @field_validator("decode_strategy")
+ @classmethod
+ def _validate_decode_strategy(cls, v: str) -> str:
+ if v not in {"greedy", "beam"}:
+ raise ValueError(f"decode_strategy must be 'greedy' or 'beam', got {v!r}")
+ return v
+
+ @field_validator("beam_width")
+ @classmethod
+ def _validate_beam_width(cls, v: int) -> int:
+ if v < 1:
+ raise ValueError(f"beam_width must be >= 1, got {v}")
+ return v
+
+ @field_validator("repetition_penalty")
+ @classmethod
+ def _validate_repetition_penalty(cls, v: float) -> float:
+ if v < 1.0:
+ raise ValueError(f"repetition_penalty must be >= 1.0 (1.0 disables it), got {v}")
+ return v
+
+
+class ComparedModelConfig(_StrictModel):
+ """One model in the Phase 3 comparison, pinned to an exact Hub commit.
+
+ ``revision`` must be a full 40-character commit SHA, never a branch or tag
+ name, so a moved branch can't silently change the model being evaluated.
+ """
+
+ # ``model_id`` matches the run_meta.json field; opt out of pydantic's
+ # protected ``model_`` namespace warning, as the API response schemas do.
+ model_config = ConfigDict(extra="forbid", protected_namespaces=())
+
+ model_id: str = Field(min_length=1)
+ hub_repo: str = Field(pattern=r"^[\w.-]+/[\w.-]+$")
+ revision: str = Field(pattern=r"^[0-9a-f]{40}$")
+
+
+class BaselineDecodeConfig(_StrictModel):
+ """Generation settings passed explicitly to every Hugging Face baseline.
+
+ Greedy decoding, so each repository's own generation defaults never apply
+ (``docs/EVAL_METHODOLOGY.md`` § 8.4).
+ """
+
+ num_beams: int = Field(default=1, ge=1)
+ do_sample: bool = False
+ max_new_tokens: int = Field(default=40, ge=1)
+ repetition_penalty: float = Field(default=1.0, ge=1.0)
+ no_repeat_ngram_size: int = Field(default=0, ge=0)
+ precision: Literal["float32"] = "float32"
+
+
+def _protocol_cnn() -> ComparedModelConfig:
+ return ComparedModelConfig(
+ model_id="inceptionv3-transformer-stabilized",
+ hub_repo="apoorvrajdev/captioning-inceptionv3-transformer",
+ revision="59d93b4babb16b0ac81eef598f3abc271a355cbf", # tag v2.0.0
+ )
+
+
+def _protocol_baselines() -> list[ComparedModelConfig]:
+ return [
+ ComparedModelConfig(
+ model_id="blip-base",
+ hub_repo="Salesforce/blip-image-captioning-base",
+ revision="82a37760796d32b1411fe092ab5d4e227313294b",
+ ),
+ ComparedModelConfig(
+ model_id="vit-gpt2",
+ hub_repo="nlpconnect/vit-gpt2-image-captioning",
+ revision="dc68f91c06a1ba6f15268e5b9c13ae7a7c514084",
+ ),
+ ComparedModelConfig(
+ model_id="git-base-coco",
+ hub_repo="microsoft/git-base-coco",
+ revision="a13141da42abd4a8cbf283601a8104265f537cee",
+ ),
+ ]
+
+
+class CompareConfig(_StrictModel):
+ """Phase 3 model comparison (ADR-019).
+
+ The defaults are the frozen protocol in ``docs/EVAL_METHODOLOGY.md`` § 8.1
+ (models and revisions) and § 8.4 (baseline decoding). Changing them is a
+ protocol amendment, not a tuning knob. The CNN + Transformer's own decoding
+ still comes from ``serve`` / the caller, exactly as in ``scripts/evaluate.py``.
+ """
+
+ cnn: ComparedModelConfig = Field(default_factory=_protocol_cnn)
+ baselines: list[ComparedModelConfig] = Field(default_factory=_protocol_baselines)
+ baseline_decode: BaselineDecodeConfig = Field(default_factory=BaselineDecodeConfig)
+
+ @model_validator(mode="after")
+ def _validate_unique_model_ids(self) -> CompareConfig:
+ ids = [self.cnn.model_id, *(m.model_id for m in self.baselines)]
+ duplicates = sorted({i for i in ids if ids.count(i) > 1})
+ if duplicates:
+ raise ValueError(f"model_id must be unique across compared models, got {duplicates}")
+ return self
+
+
+class AppConfig(BaseSettings):
+ """Top-level config aggregating every sub-config.
+
+ Loaded by ``captioning.config.loader.load_config(yaml_path)``. Env vars
+ with prefix ``CAPTIONING__`` override fields at any depth.
+ """
+
+ data: DataConfig = Field(default_factory=DataConfig)
+ model: ModelConfig = Field(default_factory=ModelConfig)
+ train: TrainConfig = Field(default_factory=TrainConfig)
+ serve: ServeConfig = Field(default_factory=ServeConfig)
+ compare: CompareConfig = Field(default_factory=CompareConfig)
+
+ model_config = SettingsConfigDict(
+ env_prefix="CAPTIONING__",
+ env_nested_delimiter="__",
+ case_sensitive=False,
+ extra="forbid", # Reject unknown keys — catches typos at load time
+ )
diff --git a/src/captioning/data/__init__.py b/src/captioning/data/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..e8cb0850ee9fbe80bbe6998a1734af10dc9163dc
--- /dev/null
+++ b/src/captioning/data/__init__.py
@@ -0,0 +1,21 @@
+"""Data — dataset loaders, splits, and tf.data pipelines.
+
+Data lives separately from preprocessing because *I/O and randomness* are
+fundamentally different concerns from pure transforms. This package owns:
+
+ coco.py Read COCO annotation JSONs into a (image_path, caption) DataFrame
+ splits.py Deterministic image-level train/val splitting (NOT caption-level —
+ preventing the same image from appearing in both splits)
+ pipeline.py Compose preprocessing + tokenization into tf.data pipelines
+"""
+
+from captioning.data.coco import load_coco_annotations
+from captioning.data.pipeline import build_train_pipeline, build_val_pipeline
+from captioning.data.splits import make_image_level_splits
+
+__all__ = [
+ "build_train_pipeline",
+ "build_val_pipeline",
+ "load_coco_annotations",
+ "make_image_level_splits",
+]
diff --git a/src/captioning/data/coco.py b/src/captioning/data/coco.py
new file mode 100644
index 0000000000000000000000000000000000000000..bc17b8a0e8534ca842138813169f1f6792cdbdeb
--- /dev/null
+++ b/src/captioning/data/coco.py
@@ -0,0 +1,92 @@
+"""Load COCO 2017 caption annotations into a ``pandas.DataFrame``.
+
+Mirrors notebook cell 2 with two small but important upgrades that don't
+change behaviour at fixed seeds:
+
+1. **Seeded sampling.** The notebook calls ``captions.sample(120000)`` with no
+ ``random_state``, so two runs produce different subsets. We thread the
+ seed through so every run is identical when the seed is fixed.
+2. **Path validation.** The notebook constructs paths via ``f-string`` with no
+ ``os.path.exists`` check; if the dataset is missing, training fails ten
+ minutes in. We check the annotations file up front and raise a clear error.
+"""
+
+from __future__ import annotations
+
+import json
+from collections.abc import Callable
+from pathlib import Path
+
+import pandas as pd
+
+from captioning.utils.logging import get_logger
+
+log = get_logger(__name__)
+
+IMAGE_FILENAME_TEMPLATE = "%012d.jpg" # Notebook cell 2: '%012d.jpg' % image_id
+
+
+def load_coco_annotations(
+ base_path: str | Path,
+ annotations_filename: str = "captions_train2017.json",
+ images_subdir: str = "train2017",
+ sample_size: int = 120_000,
+ seed: int | None = None,
+ caption_preprocessor: Callable[[str], str] | None = None,
+) -> pd.DataFrame:
+ """Read COCO annotations and return a (image, caption) DataFrame.
+
+ Mirrors notebook cell 2 + cell 4 (when ``caption_preprocessor`` is
+ supplied). Returns the same columns and dtypes the notebook produces.
+
+ Args:
+ base_path: Path to the COCO root containing ``annotations/`` and the
+ images sub-directory.
+ annotations_filename: JSON file under ``base_path / 'annotations'``.
+ images_subdir: Folder containing the JPEG files.
+ sample_size: Number of caption rows to keep after sampling. Use
+ ``-1`` to disable sampling and keep everything.
+ seed: Random seed for deterministic sampling. ``None`` matches the
+ notebook's non-deterministic behaviour.
+ caption_preprocessor: Optional function applied to the ``caption``
+ column. Pass ``preprocessing.preprocess_caption`` to reproduce
+ cell 4. Left optional so callers can stage the preprocessing
+ differently (the parity audit script applies it manually).
+
+ Returns:
+ ``pd.DataFrame`` with columns ``image`` (absolute path) and ``caption``
+ (string), index reset.
+
+ Raises:
+ FileNotFoundError: If ``annotations_filename`` is missing.
+ """
+ base_path = Path(base_path)
+ annotations_path = base_path / "annotations" / annotations_filename
+ if not annotations_path.is_file():
+ raise FileNotFoundError(
+ f"COCO annotations not found at {annotations_path}. "
+ f"Run `python -m scripts.prepare_data` to download."
+ )
+
+ log.info("loading_coco", path=str(annotations_path))
+ with annotations_path.open(encoding="utf-8") as f:
+ payload = json.load(f)
+ annotations = payload["annotations"]
+
+ img_dir = base_path / images_subdir
+ img_cap_pairs = [
+ [str(img_dir / (IMAGE_FILENAME_TEMPLATE % sample["image_id"])), sample["caption"]]
+ for sample in annotations
+ ]
+ df = pd.DataFrame(img_cap_pairs, columns=["image", "caption"])
+
+ if sample_size > 0 and sample_size < len(df):
+ df = df.sample(n=sample_size, random_state=seed)
+
+ df = df.reset_index(drop=True)
+
+ if caption_preprocessor is not None:
+ df["caption"] = df["caption"].apply(caption_preprocessor)
+
+ log.info("coco_loaded", rows=len(df), unique_images=df["image"].nunique())
+ return df
diff --git a/src/captioning/data/pipeline.py b/src/captioning/data/pipeline.py
new file mode 100644
index 0000000000000000000000000000000000000000..d8239d0afd1de096e60cde1b3f3993419675ad09
--- /dev/null
+++ b/src/captioning/data/pipeline.py
@@ -0,0 +1,92 @@
+"""``tf.data`` pipeline construction.
+
+Mirrors notebook cell 13 (the ``load_data`` map function) and cell 14 (the
+two pipeline definitions). The notebook closes over a global ``tokenizer``;
+we pass the tokenizer in explicitly so the same code works in tests, scripts,
+and the parity audit.
+
+Note on ``shuffle`` in the val pipeline: the notebook shuffles both train
+and val. That is technically unnecessary for validation but harmless, and we
+preserve it for parity. Phase 1b removes it from val.
+"""
+
+from __future__ import annotations
+
+from collections.abc import Sequence
+
+from captioning.preprocessing.image import preprocess_image_tensor
+from captioning.preprocessing.tokenizer import CaptionTokenizer
+
+
+def _make_load_data_fn(tokenizer: CaptionTokenizer):
+ """Return a ``tf.data``-compatible map function (image_path, caption) -> (image, ids).
+
+ Defined as a closure rather than a top-level function so it captures the
+ tokenizer without leaking it into the module namespace. ``tf.data`` calls
+ this for every example with both arguments as ``tf.string`` tensors.
+ """
+ import tensorflow as tf
+
+ def load_data(image_path, caption):
+ raw = tf.io.read_file(image_path)
+ image = tf.io.decode_jpeg(raw, channels=3)
+ image = preprocess_image_tensor(image)
+ ids = tokenizer.encode(caption)
+ return image, ids
+
+ return load_data
+
+
+def build_train_pipeline(
+ image_paths: Sequence[str],
+ captions: Sequence[str],
+ tokenizer: CaptionTokenizer,
+ batch_size: int,
+ buffer_size: int,
+):
+ """Build the training dataset, byte-identical to notebook cell 14.
+
+ Args:
+ image_paths: One path per (image, caption) pair (image-level split
+ already applied — see ``data.splits``).
+ captions: Preprocessed captions, one per ``image_paths`` entry.
+ tokenizer: Fitted ``CaptionTokenizer``.
+ batch_size: Mini-batch size; matches ``BATCH_SIZE`` in the notebook.
+ buffer_size: Shuffle buffer size; matches ``BUFFER_SIZE``.
+
+ Returns:
+ A ``tf.data.Dataset`` yielding ``(image, token_ids)`` batches.
+ """
+ import tensorflow as tf
+
+ load_data = _make_load_data_fn(tokenizer)
+ return (
+ tf.data.Dataset.from_tensor_slices((list(image_paths), list(captions)))
+ .map(load_data, num_parallel_calls=tf.data.AUTOTUNE)
+ .shuffle(buffer_size)
+ .batch(batch_size)
+ )
+
+
+def build_val_pipeline(
+ image_paths: Sequence[str],
+ captions: Sequence[str],
+ tokenizer: CaptionTokenizer,
+ batch_size: int,
+ buffer_size: int,
+):
+ """Build the validation dataset.
+
+ Identical structure to ``build_train_pipeline``, with a separate function
+ so Phase 1b can drop the (unnecessary) shuffle from val without coupling
+ the change to train.
+ """
+ import tensorflow as tf
+
+ load_data = _make_load_data_fn(tokenizer)
+ return (
+ tf.data.Dataset.from_tensor_slices((list(image_paths), list(captions)))
+ .map(load_data, num_parallel_calls=tf.data.AUTOTUNE)
+ .shuffle(buffer_size) # Notebook cell 14 shuffles val too — preserved.
+ .batch(batch_size)
+ )
diff --git a/src/captioning/data/splits.py b/src/captioning/data/splits.py
new file mode 100644
index 0000000000000000000000000000000000000000..14604449839cc06acfeb17e7359a49bc6c40a0c1
--- /dev/null
+++ b/src/captioning/data/splits.py
@@ -0,0 +1,86 @@
+"""Image-level train/val splitting.
+
+Mirrors notebook cell 11. The split is intentionally at the *image* level
+(not the caption level): every image owns ~5 captions in COCO, and putting
+some of an image's captions in train and others in val would be data leakage.
+
+The notebook does this correctly via the ``img_to_cap_vector`` defaultdict
+loop; we preserve that exact algorithm but inject the seed so the split is
+reproducible across runs.
+"""
+
+from __future__ import annotations
+
+import collections
+import random
+
+import pandas as pd
+
+from captioning.utils.logging import get_logger
+
+log = get_logger(__name__)
+
+
+def make_image_level_splits(
+ captions: pd.DataFrame,
+ train_fraction: float = 0.8,
+ seed: int | None = None,
+) -> tuple[list[str], list[str], list[str], list[str]]:
+ """Split captions into train/val while keeping all of an image's
+ captions in the same split.
+
+ Mirrors notebook cell 11 exactly when ``seed`` is the same value that was
+ fed to ``random.seed`` before the notebook ran. ``seed=None`` reproduces
+ the notebook's non-deterministic behaviour.
+
+ Args:
+ captions: DataFrame with ``image`` and ``caption`` columns
+ (preprocessed if you want preprocessed splits — the loader applies
+ ``preprocess_caption`` upstream).
+ train_fraction: Fraction of *unique images* assigned to the train
+ split. The notebook uses ``int(len(img_keys) * 0.8)``, which we
+ preserve byte-for-byte (``int()`` truncates, not rounds).
+ seed: If provided, used to seed Python's ``random`` for the shuffle.
+
+ Returns:
+ Tuple ``(train_imgs, train_captions, val_imgs, val_captions)`` where
+ each list has one entry per (image, caption) pair, expanded so an
+ image with N captions appears N times.
+ """
+ img_to_cap = collections.defaultdict(list)
+ for img, cap in zip(captions["image"], captions["caption"], strict=True):
+ img_to_cap[img].append(cap)
+
+ img_keys = list(img_to_cap.keys())
+
+ if seed is not None:
+ rng = random.Random(seed) # — seeded RNG is reproducible by design
+ rng.shuffle(img_keys)
+ else:
+ random.shuffle(img_keys)
+
+ slice_index = int(len(img_keys) * train_fraction)
+ train_keys, val_keys = img_keys[:slice_index], img_keys[slice_index:]
+
+ train_imgs: list[str] = []
+ train_captions: list[str] = []
+ for k in train_keys:
+ n = len(img_to_cap[k])
+ train_imgs.extend([k] * n)
+ train_captions.extend(img_to_cap[k])
+
+ val_imgs: list[str] = []
+ val_captions: list[str] = []
+ for k in val_keys:
+ n = len(img_to_cap[k])
+ val_imgs.extend([k] * n)
+ val_captions.extend(img_to_cap[k])
+
+ log.info(
+ "splits_made",
+ train_images=len(train_keys),
+ val_images=len(val_keys),
+ train_captions=len(train_captions),
+ val_captions=len(val_captions),
+ )
+ return train_imgs, train_captions, val_imgs, val_captions
diff --git a/src/captioning/evaluation/__init__.py b/src/captioning/evaluation/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..b32a1b044245d9ace100d26a3ccc6183058b5e5f
--- /dev/null
+++ b/src/captioning/evaluation/__init__.py
@@ -0,0 +1,90 @@
+"""Evaluation — caption-quality metrics + per-sample diagnostics.
+
+Available metrics (all corpus-level, 0-100 scale where applicable):
+ * BLEU-1..4 — :mod:`bleu`
+ * ROUGE-L — :mod:`rouge`
+ * METEOR — :mod:`meteor` (requires a JRE on PATH)
+ * CIDEr — :mod:`cider` (requires >= 2 examples)
+
+:func:`compute_all_metrics` in :mod:`runner` is the single entry point used
+by the CLI and by future Phase 3 benchmark comparisons; per-sample
+diagnostics live in :mod:`inspection`. Phase 3 latency timing lives in
+:mod:`latency`, and the dashboard data export in :mod:`dashboard`.
+"""
+
+from captioning.evaluation.benchmark import RunMeta, write_run_artifacts
+from captioning.evaluation.bleu import (
+ BleuBreakdown,
+ corpus_bleu_breakdown,
+ corpus_bleu_score,
+)
+from captioning.evaluation.cider import MIN_SAMPLES_FOR_CIDER, corpus_cider_score
+from captioning.evaluation.comparison import (
+ ComparisonError,
+ RunRecord,
+ build_summary,
+ load_run,
+ render_markdown,
+)
+from captioning.evaluation.dashboard import (
+ DashboardExportError,
+ build_dashboard_data,
+ render_dashboard_json,
+)
+from captioning.evaluation.inspection import (
+ SampleDiagnostics,
+ diagnose_many,
+ diagnose_sample,
+ format_diagnostic_row,
+ write_diagnostics_jsonl,
+)
+from captioning.evaluation.latency import (
+ BatchLatency,
+ LatencyBenchmarkError,
+ LatencySettings,
+ measure_latency,
+ runtime_info,
+ summarize,
+ time_load,
+)
+from captioning.evaluation.meteor import corpus_meteor_score
+from captioning.evaluation.rouge import corpus_rouge_l_score
+from captioning.evaluation.runner import MetricsReport, compute_all_metrics
+from captioning.evaluation.slice import EvalSlice, load_eval_slice, slice_fingerprint
+
+__all__ = [
+ "MIN_SAMPLES_FOR_CIDER",
+ "BatchLatency",
+ "BleuBreakdown",
+ "ComparisonError",
+ "DashboardExportError",
+ "EvalSlice",
+ "LatencyBenchmarkError",
+ "LatencySettings",
+ "MetricsReport",
+ "RunMeta",
+ "RunRecord",
+ "SampleDiagnostics",
+ "build_dashboard_data",
+ "build_summary",
+ "compute_all_metrics",
+ "corpus_bleu_breakdown",
+ "corpus_bleu_score",
+ "corpus_cider_score",
+ "corpus_meteor_score",
+ "corpus_rouge_l_score",
+ "diagnose_many",
+ "diagnose_sample",
+ "format_diagnostic_row",
+ "load_eval_slice",
+ "load_run",
+ "measure_latency",
+ "render_dashboard_json",
+ "render_markdown",
+ "runtime_info",
+ "slice_fingerprint",
+ "summarize",
+ "time_load",
+ "write_diagnostics_jsonl",
+ "write_run_artifacts",
+]
diff --git a/src/captioning/evaluation/benchmark.py b/src/captioning/evaluation/benchmark.py
new file mode 100644
index 0000000000000000000000000000000000000000..cad12649b6456807c4181c828db99b5a87f07d95
--- /dev/null
+++ b/src/captioning/evaluation/benchmark.py
@@ -0,0 +1,128 @@
+"""Benchmark-ready run artefacts.
+
+Every evaluation pass writes a consistent set of files under
+``//`` so Phase 3 cross-model comparisons can join them
+without bespoke parsing per model:
+
+ metrics.json — :class:`MetricsReport` dumped via dataclass-asdict
+ predictions.jsonl — one row per (image, prediction, references)
+ diagnostics.jsonl — one :class:`SampleDiagnostics` per row
+ run_meta.json — model id, decode strategy, n_samples, timestamp
+ report.md — Markdown summary humans actually read
+
+A "run" is one (model, decode_strategy, dataset_slice) tuple. ``run_id`` is
+a free-form string — the CLI defaults to a timestamp; comparison code groups
+by ``model_id`` to plot bars across models.
+"""
+
+from __future__ import annotations
+
+import json
+from dataclasses import dataclass, field
+from datetime import datetime, timezone
+from pathlib import Path
+
+from captioning.evaluation.inspection import SampleDiagnostics, write_diagnostics_jsonl
+from captioning.evaluation.runner import MetricsReport
+
+
+@dataclass(frozen=True)
+class RunMeta:
+ """Per-evaluation-run metadata persisted next to metrics."""
+
+ model_id: str
+ decode_strategy: str
+ weights_path: str
+ tokenizer_dir: str
+ n_samples: int
+ max_length: int
+ beam_width: int | None = None
+ length_penalty: float | None = None
+ repetition_penalty: float | None = None
+ timestamp_utc: str = field(default_factory=lambda: datetime.now(timezone.utc).isoformat())
+
+ def to_dict(self) -> dict[str, object]:
+ return {
+ "model_id": self.model_id,
+ "decode_strategy": self.decode_strategy,
+ "weights_path": self.weights_path,
+ "tokenizer_dir": self.tokenizer_dir,
+ "n_samples": self.n_samples,
+ "max_length": self.max_length,
+ "beam_width": self.beam_width,
+ "length_penalty": self.length_penalty,
+ "repetition_penalty": self.repetition_penalty,
+ "timestamp_utc": self.timestamp_utc,
+ }
+
+
+def write_run_artifacts(
+ run_dir: str | Path,
+ *,
+ metrics: MetricsReport,
+ meta: RunMeta,
+ images: list[str],
+ predictions: list[str],
+ references: list[list[str]],
+ diagnostics: list[SampleDiagnostics],
+) -> Path:
+ """Write every benchmark artefact to ``run_dir`` and return the directory.
+
+ Idempotent over a clean ``run_dir``; overwrites existing files inside.
+ """
+ out = Path(run_dir)
+ out.mkdir(parents=True, exist_ok=True)
+
+ (out / "metrics.json").write_text(json.dumps(metrics.to_dict(), indent=2), encoding="utf-8")
+ (out / "run_meta.json").write_text(json.dumps(meta.to_dict(), indent=2), encoding="utf-8")
+
+ with (out / "predictions.jsonl").open("w", encoding="utf-8") as f:
+ for img, pred, refs in zip(images, predictions, references, strict=True):
+ row = {"image": img, "prediction": pred, "references": list(refs)}
+ f.write(json.dumps(row, ensure_ascii=False) + "\n")
+
+ write_diagnostics_jsonl(diagnostics, out / "diagnostics.jsonl")
+ (out / "report.md").write_text(_render_report_markdown(meta, metrics), encoding="utf-8")
+ return out
+
+
+def _render_report_markdown(meta: RunMeta, m: MetricsReport) -> str:
+ """Render the human-facing Markdown summary of a single run."""
+
+ def fmt(v: float | None) -> str:
+ return "n/a" if v is None else f"{v:.2f}"
+
+ lines = [
+ f"# Evaluation run — {meta.model_id}",
+ "",
+ f"- Decode strategy: `{meta.decode_strategy}`",
+ f"- Weights: `{meta.weights_path}`",
+ f"- Tokenizer dir: `{meta.tokenizer_dir}`",
+ f"- Samples: **{meta.n_samples}**",
+ f"- Timestamp (UTC): {meta.timestamp_utc}",
+ ]
+ if meta.beam_width is not None:
+ lines.append(f"- Beam width: {meta.beam_width}")
+ if meta.length_penalty is not None:
+ lines.append(f"- Length penalty: {meta.length_penalty}")
+ if meta.repetition_penalty is not None:
+ lines.append(f"- Repetition penalty: {meta.repetition_penalty}")
+ lines += [
+ "",
+ "## Metrics",
+ "",
+ "| Metric | Value |",
+ "|---|---|",
+ f"| BLEU-1 | {fmt(m.bleu1)} |",
+ f"| BLEU-2 | {fmt(m.bleu2)} |",
+ f"| BLEU-3 | {fmt(m.bleu3)} |",
+ f"| BLEU-4 | {fmt(m.bleu4)} |",
+ f"| ROUGE-L | {fmt(m.rouge_l)} |",
+ f"| METEOR | {fmt(m.meteor)} |",
+ f"| CIDEr | {fmt(m.cider)} |",
+ ]
+ if m.errors:
+ lines += ["", "## Skipped or failed metrics", ""]
+ for name, err in m.errors.items():
+ lines.append(f"- `{name}`: {err}")
+ return "\n".join(lines) + "\n"
diff --git a/src/captioning/evaluation/bleu.py b/src/captioning/evaluation/bleu.py
new file mode 100644
index 0000000000000000000000000000000000000000..3cd91dd875d55dc70d3597a4ccb9656f25213b0d
--- /dev/null
+++ b/src/captioning/evaluation/bleu.py
@@ -0,0 +1,108 @@
+"""Corpus BLEU score.
+
+The IEEE paper reports BLEU-4 ~24 on COCO val. ``sacrebleu`` is the de-facto
+BLEU implementation; NLTK's BLEU has idiosyncratic smoothing and would not
+reproduce the published number across machines.
+
+``corpus_bleu_score`` returns BLEU-4 (the default n=4 score) so existing
+callers keep working. ``corpus_bleu_breakdown`` additionally exposes BLEU-1,
+BLEU-2, BLEU-3, BLEU-4 in one pass — useful for the inspection utility and
+for the JSON report consumed by Phase 3 cross-model comparison.
+"""
+
+from __future__ import annotations
+
+from collections.abc import Sequence
+from dataclasses import dataclass
+
+from captioning.evaluation.tokenization import (
+ strip_sentinels_many,
+ strip_sentinels_references,
+)
+
+
+@dataclass(frozen=True)
+class BleuBreakdown:
+ """Per-n BLEU precisions plus the overall BLEU-4 score (0-100 scale)."""
+
+ bleu1: float
+ bleu2: float
+ bleu3: float
+ bleu4: float
+
+
+def _refs_by_slot(references: Sequence[Sequence[str]]) -> list[list[str]]:
+ """Convert ragged per-example references to sacrebleu's per-slot layout."""
+ max_refs = max(len(r) for r in references) if references else 0
+ return [[refs[i] if i < len(refs) else "" for refs in references] for i in range(max_refs)]
+
+
+def corpus_bleu_score(
+ predictions: Sequence[str],
+ references: Sequence[Sequence[str]],
+) -> float:
+ """Compute corpus BLEU-4 via ``sacrebleu``.
+
+ Args:
+ predictions: One generated caption per evaluation example.
+ references: One *list* of reference captions per evaluation example.
+ COCO has up to 5 references per image; pad shorter lists with the
+ empty string ``""`` if needed (sacrebleu handles ragged lists).
+
+ Returns:
+ BLEU-4 in the 0-100 range (sacrebleu's convention; multiply by 1
+ to compare with NLTK's 0-1 range — they're not interchangeable).
+
+ Raises:
+ ImportError: If sacrebleu is not installed. Install via the eval
+ extras: ``pip install -e ".[eval]"`` or the requirements file.
+ """
+ return corpus_bleu_breakdown(predictions, references).bleu4
+
+
+def corpus_bleu_breakdown(
+ predictions: Sequence[str],
+ references: Sequence[Sequence[str]],
+) -> BleuBreakdown:
+ """Compute BLEU-1, BLEU-2, BLEU-3, BLEU-4 in a single pass.
+
+ Args:
+ predictions: One generated caption per example.
+ references: One *list* of reference captions per example.
+
+ Returns:
+ :class:`BleuBreakdown` with all four cumulative BLEU-n scores on the
+ 0-100 scale (sacrebleu's convention).
+
+ Raises:
+ ImportError: If sacrebleu is not installed.
+ ValueError: On mismatched lengths.
+ """
+ try:
+ import sacrebleu
+ except ImportError as e:
+ raise ImportError(
+ "sacrebleu is required for BLEU evaluation. "
+ "Install it via `pip install -r requirements-eval.txt`."
+ ) from e
+
+ if len(predictions) != len(references):
+ raise ValueError(
+ f"predictions ({len(predictions)}) and references "
+ f"({len(references)}) must have the same length"
+ )
+
+ preds = strip_sentinels_many(predictions)
+ refs = strip_sentinels_references(references)
+ refs_by_slot = _refs_by_slot(refs)
+
+ # ``corpus_bleu`` only returns BLEU-4. To get cumulative BLEU-1..3 we
+ # instantiate ``BLEU`` directly with ``max_ngram_order=n``, which weights
+ # the geometric mean over precisions[:n] (same convention as NLTK's
+ # cumulative BLEU and the COCO eval scripts).
+ bleu_cls = sacrebleu.metrics.BLEU
+ scores: list[float] = []
+ for n in (1, 2, 3, 4):
+ scorer = bleu_cls(max_ngram_order=n, effective_order=True)
+ scores.append(float(scorer.corpus_score(preds, refs_by_slot).score))
+ return BleuBreakdown(bleu1=scores[0], bleu2=scores[1], bleu3=scores[2], bleu4=scores[3])
diff --git a/src/captioning/evaluation/cider.py b/src/captioning/evaluation/cider.py
new file mode 100644
index 0000000000000000000000000000000000000000..23bdd3936b9c7b5ae8721dcc66dc122b92dbf3df
--- /dev/null
+++ b/src/captioning/evaluation/cider.py
@@ -0,0 +1,81 @@
+"""CIDEr (Consensus-based Image Description Evaluation) corpus metric.
+
+CIDEr is the metric the COCO captioning leaderboard ranks by. It computes a
+TF-IDF weighting over n-grams of the references and measures cosine similarity
+to the prediction. Higher is better; correctly trained models score in the
+range 0.6 - 1.4 on COCO val.
+
+Implementation notes:
+ * We delegate to ``pycocoevalcap`` — the reference implementation used by
+ the original CIDEr paper and by every COCO submission.
+ * CIDEr's TF-IDF is corpus-level: scoring a *single* example returns 0
+ because every n-gram is "common" to that one-document corpus. The
+ ``runner`` aggregator and the CLI guard against calling CIDEr with
+ fewer than ``MIN_SAMPLES_FOR_CIDER`` examples and return ``None``
+ in that case.
+"""
+
+from __future__ import annotations
+
+from collections.abc import Sequence
+
+from captioning.evaluation.tokenization import (
+ strip_sentinels_many,
+ strip_sentinels_references,
+)
+
+# CIDEr's TF-IDF is degenerate below this — every n-gram is "common"
+# to the entire corpus, so the score collapses to 0. We surface ``None``
+# instead of a misleading value below this threshold.
+MIN_SAMPLES_FOR_CIDER = 2
+
+
+def corpus_cider_score(
+ predictions: Sequence[str],
+ references: Sequence[Sequence[str]],
+) -> float:
+ """Compute corpus CIDEr.
+
+ Args:
+ predictions: One generated caption per example.
+ references: One *list* of reference captions per example.
+
+ Returns:
+ CIDEr in the 0-10 range (pycocoevalcap convention; the typical COCO
+ leaderboard value is in [0, 2]).
+
+ Raises:
+ ImportError: If ``pycocoevalcap`` is not installed.
+ ValueError: On mismatched lengths or if called with fewer than
+ ``MIN_SAMPLES_FOR_CIDER`` examples (in which case CIDEr's TF-IDF
+ is degenerate and the score is meaningless).
+ """
+ if len(predictions) != len(references):
+ raise ValueError(
+ f"predictions ({len(predictions)}) and references "
+ f"({len(references)}) must have the same length"
+ )
+ if len(predictions) < MIN_SAMPLES_FOR_CIDER:
+ raise ValueError(
+ f"CIDEr requires at least {MIN_SAMPLES_FOR_CIDER} examples; "
+ f"got {len(predictions)}. TF-IDF is degenerate on smaller corpora."
+ )
+
+ try:
+ from pycocoevalcap.cider.cider import Cider
+ except ImportError as e:
+ raise ImportError(
+ "pycocoevalcap is required for CIDEr evaluation. "
+ "Install via `pip install -r requirements-eval.txt`."
+ ) from e
+
+ preds = strip_sentinels_many(predictions)
+ refs = strip_sentinels_references(references)
+
+ # pycocoevalcap expects {image_id: [captions]} dicts.
+ gts = {str(i): [r for r in ref_list if r] for i, ref_list in enumerate(refs)}
+ res = {str(i): [p] for i, p in enumerate(preds)}
+
+ scorer = Cider()
+ score, _ = scorer.compute_score(gts, res)
+ return float(score)
diff --git a/src/captioning/evaluation/comparison.py b/src/captioning/evaluation/comparison.py
new file mode 100644
index 0000000000000000000000000000000000000000..41992f081af03c2e817e9a874bc1e97547ca60ec
--- /dev/null
+++ b/src/captioning/evaluation/comparison.py
@@ -0,0 +1,310 @@
+"""Join Phase 3 run directories into one cross-model comparison summary.
+
+Every compared run must score the same slice: the same image file names, in
+the same order, with the same references (``docs/EVAL_METHODOLOGY.md`` § 8.2).
+Identity is the slice fingerprint, recomputed from each run's
+``predictions.jsonl`` and checked against what its ``comparison_meta.json``
+records (fingerprint, counts, protocol, normalisation). Nothing is repaired:
+any disagreement raises :class:`ComparisonError` naming the run.
+
+Committed runs made before the comparison runner existed (the CNN +
+Transformer rows of § 8.4) have no ``comparison_meta.json``. They are loaded
+only when asked for explicitly, as labelled reference rows identified by the
+same fingerprint. Metric values are copied verbatim from each ``metrics.json``.
+"""
+
+from __future__ import annotations
+
+import json
+from collections.abc import Sequence
+from dataclasses import dataclass
+from pathlib import Path
+from typing import Any, TypeVar
+
+from pydantic import BaseModel, ConfigDict, ValidationError
+
+from captioning.evaluation.slice import load_eval_slice, slice_fingerprint
+
+METRIC_KEYS = ("bleu1", "bleu2", "bleu3", "bleu4", "rouge_l", "meteor", "cider")
+METRIC_LABELS = ("BLEU-1", "BLEU-2", "BLEU-3", "BLEU-4", "ROUGE-L", "METEOR", "CIDEr")
+OVERLAP_CAVEAT = (
+ "The slice comes from COCO train2017. The CNN + Transformer held these images out of "
+ "training; the Hugging Face baselines were fine-tuned on COCO training data (ViT-GPT2 "
+ "possibly), so they may have seen them. These scores are not a held-out, like-for-like "
+ "comparison (docs/EVAL_METHODOLOGY.md § 8.5)."
+)
+
+
+class ComparisonError(ValueError):
+ """Runs can't be compared: a run is incomplete, malformed or on another slice."""
+
+
+class _Artefact(BaseModel):
+ model_config = ConfigDict(extra="forbid", protected_namespaces=())
+
+
+class _Metrics(_Artefact):
+ n_examples: int
+ bleu1: float | None
+ bleu2: float | None
+ bleu3: float | None
+ bleu4: float | None
+ rouge_l: float | None
+ meteor: float | None
+ cider: float | None
+ errors: dict[str, str]
+
+
+class _RunMeta(_Artefact):
+ model_id: str
+ decode_strategy: str
+ weights_path: str
+ tokenizer_dir: str
+ n_samples: int
+ max_length: int
+ beam_width: int | None
+ length_penalty: float | None
+ repetition_penalty: float | None
+ timestamp_utc: str
+
+
+class _SliceMeta(_Artefact):
+ source: str
+ fingerprint_sha256: str
+ images: int
+ references: int
+
+
+class _MetricFlags(_Artefact):
+ meteor: bool
+ cider: bool
+
+
+class _ComparisonMeta(_Artefact):
+ protocol: str
+ model_id: str
+ backend: str
+ captioner: str
+ hub_repo: str | None
+ revision: str | None
+ decode_settings: dict[str, Any]
+ normalisation: str
+ slice: _SliceMeta
+ batch_size: int
+ device: str | None
+ seed: int
+ metrics: _MetricFlags
+
+
+@dataclass(frozen=True)
+class RunRecord:
+ """One validated run directory, ready to compare."""
+
+ run_id: str
+ metrics: _Metrics
+ run_meta: _RunMeta
+ comparison_meta: _ComparisonMeta | None # None for a pre-harness reference run
+ fingerprint: str
+ images: int
+ references: int
+
+
+_ModelT = TypeVar("_ModelT", bound=BaseModel)
+
+
+def load_run(run_dir: str | Path, *, reference: bool = False) -> RunRecord:
+ """Read and check one run directory.
+
+ Args:
+ run_dir: A ``results//`` directory.
+ reference: ``True`` for a committed run made before the comparison
+ runner, which has no ``comparison_meta.json``.
+
+ Raises:
+ ComparisonError: If a file is missing or malformed, or the run's files
+ disagree with each other about the slice.
+ """
+ run_dir = Path(run_dir)
+ run_id = run_dir.name
+ required = ["predictions.jsonl", "metrics.json", "run_meta.json"]
+ if not reference:
+ required.append("comparison_meta.json")
+ missing = [name for name in required if not (run_dir / name).is_file()]
+ if missing:
+ raise ComparisonError(f"{run_id}: missing {', '.join(missing)}")
+
+ metrics = _parse(run_dir / "metrics.json", _Metrics, run_id)
+ run_meta = _parse(run_dir / "run_meta.json", _RunMeta, run_id)
+ meta = None if reference else _parse(run_dir / "comparison_meta.json", _ComparisonMeta, run_id)
+ try:
+ eval_slice = load_eval_slice(run_dir / "predictions.jsonl", ".")
+ except ValueError as exc: # includes JSON decoding errors
+ raise ComparisonError(f"{run_id}: predictions.jsonl is malformed: {exc}") from exc
+
+ images = len(eval_slice)
+ references = sum(len(refs) for refs in eval_slice.references)
+ fingerprint = slice_fingerprint(eval_slice)
+ counts = {
+ "run_meta.json n_samples": run_meta.n_samples,
+ "metrics.json n_examples": metrics.n_examples,
+ }
+ if meta is not None:
+ counts["comparison_meta.json slice.images"] = meta.slice.images
+ for label, value in counts.items():
+ if value != images:
+ raise ComparisonError(
+ f"{run_id}: {label} is {value}, but predictions.jsonl has {images} images"
+ )
+ if meta is not None:
+ if meta.slice.references != references:
+ raise ComparisonError(
+ f"{run_id}: comparison_meta.json slice.references is {meta.slice.references}, "
+ f"but predictions.jsonl has {references} references"
+ )
+ if meta.slice.fingerprint_sha256 != fingerprint:
+ raise ComparisonError(
+ f"{run_id}: comparison_meta.json records slice fingerprint "
+ f"{meta.slice.fingerprint_sha256}, but predictions.jsonl gives {fingerprint}"
+ )
+ if meta.model_id != run_meta.model_id:
+ raise ComparisonError(
+ f"{run_id}: comparison_meta.json model_id {meta.model_id!r} "
+ f"differs from run_meta.json ({run_meta.model_id!r})"
+ )
+ return RunRecord(run_id, metrics, run_meta, meta, fingerprint, images, references)
+
+
+def build_summary(runs: Sequence[RunRecord]) -> dict[str, Any]:
+ """Check that ``runs`` are comparable and return the comparison summary.
+
+ Rows are sorted by model id, decoding and run id, so the summary doesn't
+ depend on the order the runs were given in.
+
+ Raises:
+ ComparisonError: If no runs are given, two runs share a model and
+ decoding, or any run differs in slice, protocol or normalisation.
+ """
+ if not runs:
+ raise ComparisonError("no runs to compare")
+ ordered = sorted(
+ runs, key=lambda r: (r.run_meta.model_id, r.run_meta.decode_strategy, r.run_id)
+ )
+ base = ordered[0]
+ seen: dict[tuple[str, str], str] = {}
+ for run in ordered:
+ key = (run.run_meta.model_id, run.run_meta.decode_strategy)
+ if key in seen:
+ raise ComparisonError(
+ f"{run.run_id}: duplicates {seen[key]} (model {key[0]}, {key[1]} decoding)"
+ )
+ seen[key] = run.run_id
+ for label, value, expected in (
+ ("image count", run.images, base.images),
+ ("reference count", run.references, base.references),
+ ("slice fingerprint", run.fingerprint, base.fingerprint),
+ ):
+ if value != expected:
+ raise ComparisonError(
+ f"{run.run_id}: {label} {value} differs from {base.run_id} ({expected})"
+ )
+
+ harness_runs = [r for r in ordered if r.comparison_meta is not None]
+ for run in harness_runs[1:]:
+ for label in ("protocol", "normalisation"):
+ value = getattr(run.comparison_meta, label)
+ expected = getattr(harness_runs[0].comparison_meta, label)
+ if value != expected:
+ raise ComparisonError(
+ f"{run.run_id}: {label} {value!r} differs from "
+ f"{harness_runs[0].run_id} ({expected!r})"
+ )
+ first_meta = harness_runs[0].comparison_meta if harness_runs else None
+
+ return {
+ "protocol": first_meta.protocol if first_meta else None,
+ "normalisation": first_meta.normalisation if first_meta else None,
+ "slice": {
+ "fingerprint_sha256": base.fingerprint,
+ "images": base.images,
+ "references": base.references,
+ "references_per_image": round(base.references / base.images, 2),
+ },
+ "caveat": OVERLAP_CAVEAT,
+ "metric_keys": list(METRIC_KEYS),
+ "rows": [_row(run) for run in ordered],
+ }
+
+
+def render_markdown(summary: dict[str, Any]) -> str:
+ """Render the human-readable table for a :func:`build_summary` result."""
+ s = summary["slice"]
+ lines = [
+ "# Phase 3 model comparison",
+ "",
+ f"- Protocol: {summary['protocol'] or 'not recorded (reference runs only)'}",
+ f"- Slice: {s['images']} images, {s['references']} references "
+ f"(about {s['references_per_image']:.2f} per image), "
+ f"fingerprint `{s['fingerprint_sha256']}`",
+ f"- Normalisation: {summary['normalisation'] or 'not recorded (reference runs only)'}",
+ "",
+ f"> {summary['caveat']}",
+ "",
+ "| Run | Model | Decoding | Revision | Samples | " + " | ".join(METRIC_LABELS) + " |",
+ "|---|---|---|---|---|" + "---|" * len(METRIC_LABELS),
+ ]
+ for row in summary["rows"]:
+ run = f"`{row['run_id']}`" + (" (reference)" if row["kind"] == "reference" else "")
+ revision = f"`{row['revision'][:7]}`" if row["revision"] else "—"
+ values = " | ".join(_fmt(row["metrics"][key]) for key in METRIC_KEYS)
+ lines.append(
+ f"| {run} | {row['model_id']} | {row['decode_strategy']} | {revision} | "
+ f"{row['n_samples']} | {values} |"
+ )
+ lines += [
+ "",
+ "Values are rounded to two decimals; `comparison.json` holds the exact values "
+ "from each run's `metrics.json`.",
+ "",
+ ]
+ return "\n".join(lines)
+
+
+def _row(run: RunRecord) -> dict[str, Any]:
+ meta, run_meta = run.comparison_meta, run.run_meta
+ decode_settings = (
+ meta.decode_settings
+ if meta is not None
+ else {
+ "beam_width": run_meta.beam_width,
+ "length_penalty": run_meta.length_penalty,
+ "repetition_penalty": run_meta.repetition_penalty,
+ "max_length": run_meta.max_length,
+ }
+ )
+ return {
+ "run_id": run.run_id,
+ "kind": "reference" if meta is None else "phase3",
+ "model_id": run_meta.model_id,
+ "backend": meta.backend if meta else None,
+ "captioner": meta.captioner if meta else None,
+ "hub_repo": meta.hub_repo if meta else None,
+ "revision": meta.revision if meta else None,
+ "weights_path": run_meta.weights_path,
+ "decode_strategy": run_meta.decode_strategy,
+ "decode_settings": decode_settings,
+ "n_samples": run_meta.n_samples,
+ "metrics": {key: getattr(run.metrics, key) for key in METRIC_KEYS},
+ "metric_errors": run.metrics.errors,
+ }
+
+
+def _parse(path: Path, model: type[_ModelT], run_id: str) -> _ModelT:
+ try:
+ return model.model_validate(json.loads(path.read_text(encoding="utf-8")))
+ except (ValueError, ValidationError) as exc:
+ detail = str(exc).splitlines()[0] if str(exc) else type(exc).__name__
+ raise ComparisonError(f"{run_id}: {path.name} is malformed: {detail}") from exc
+
+
+def _fmt(value: float | None) -> str:
+ return "n/a" if value is None else f"{value:.2f}"
diff --git a/src/captioning/evaluation/dashboard.py b/src/captioning/evaluation/dashboard.py
new file mode 100644
index 0000000000000000000000000000000000000000..64960c9c95bc468672da8f3f94f4896752ec6a43
--- /dev/null
+++ b/src/captioning/evaluation/dashboard.py
@@ -0,0 +1,416 @@
+"""Export the Phase 3 dashboard data from committed results.
+
+The SPA's comparison dashboard reads one static JSON file, imported at build
+time (ADR-021). This module builds it from two committed sources and nothing
+else:
+
+- the cross-run quality summary, ``results//comparison.json``
+ (TASK-013, ``docs/EVAL_METHODOLOGY.md`` § 8);
+- every latency run, ``results/--/latency.json``
+ (TASK-015, § 9).
+
+Values are copied verbatim, never recomputed or rounded. The only hand-written
+content is each model's display name and the caveat notes, which restate
+§§ 8 and 9. The sources are checked before anything is exported: quality and
+latency must share the slice, every latency run must use the same protocol,
+inputs, settings and timing, every summary must recompute from its raw
+samples, and a model's Hub id and revision must agree across all its runs.
+Any disagreement raises :class:`DashboardExportError` naming the run.
+"""
+
+from __future__ import annotations
+
+import json
+from collections.abc import Sequence
+from pathlib import Path
+from typing import Any, TypeVar
+
+from pydantic import BaseModel, ConfigDict, ValidationError
+
+from captioning.evaluation.comparison import METRIC_KEYS, METRIC_LABELS
+from captioning.evaluation.latency import summarize
+
+DASHBOARD_SCHEMA_VERSION = 1
+DEFAULT_COMPARISON_ID = "phase3-comparison"
+DEFAULT_LATENCY_PREFIX = "phase3-latency-"
+EXPORT_COMMAND = "python -m scripts.export_dashboard_data"
+
+# Names shown in the dashboard, keyed by the § 8.1 model id.
+DISPLAY_NAMES = {
+ "blip-base": "BLIP-base",
+ "git-base-coco": "GIT-base-coco",
+ "inceptionv3-transformer-stabilized": "CNN + Transformer (InceptionV3)",
+ "vit-gpt2": "ViT-GPT2",
+}
+# How each adapter handles a batch (§ 9.5): one generate() call for the whole
+# batch, or one single-image prediction after another.
+BATCH_MODES = {"CNNCaptioner": "sequential", "HFCaptioner": "batched"}
+
+QUALITY_NOTES = (
+ "Scores use the slice's stored references (about {rpi:.2f} per image), not the "
+ "five-reference COCO setup, so they can't be compared with published COCO results "
+ "(docs/EVAL_METHODOLOGY.md § 8.8).",
+ 'Rows of kind "reference" are committed CNN + Transformer runs made before the comparison '
+ "harness, so they record no revision (null). The greedy one is reproduced exactly by a "
+ "harness run at the pinned revision (docs/EVAL_METHODOLOGY.md § 8.8). The beam-search row "
+ "is a labelled reference and isn't compared with the greedy baselines "
+ "(docs/EVAL_METHODOLOGY.md § 8.4).",
+ "Models are listed by model id. The order is not a ranking.",
+)
+LATENCY_NOTES = (
+ "Values are seconds per call, and one call captions one whole batch, so a batch-8 value is "
+ "the time for eight images, not per image (docs/EVAL_METHODOLOGY.md § 9.4).",
+ 'Runs with batch_mode "sequential" (the CNN + Transformer) caption a batch one image at a '
+ "time: their batch-8 values are eight single-image calls in a row, not batched inference, "
+ "and aren't like-for-like with the batched Hugging Face values (docs/EVAL_METHODOLOGY.md "
+ "§ 9.5).",
+ "Each device's runs come from a different host, operating system and framework build (see "
+ "each run's environment). Figures compare only within one environment and device; together "
+ "they are not a controlled CPU-versus-GPU comparison (docs/EVAL_METHODOLOGY.md §§ 9.5, 9.10).",
+ "load_seconds is the cold-start cost on that host: captioner construction plus load(), "
+ "including framework imports and any download. It is never part of a sample "
+ "(docs/EVAL_METHODOLOGY.md § 9.1).",
+ "Latency says nothing about caption quality (docs/EVAL_METHODOLOGY.md § 9.4).",
+)
+
+
+class DashboardExportError(ValueError):
+ """The committed results can't be exported: a file is missing, malformed or inconsistent."""
+
+
+class _Artefact(BaseModel):
+ # Strict: a malformed value (a number stored as a string) is refused, not converted.
+ model_config = ConfigDict(extra="forbid", strict=True, protected_namespaces=())
+
+
+# A copied number keeps its JSON type: an int is never widened to a float.
+_Number = int | float
+
+
+class _ComparisonSlice(_Artefact):
+ fingerprint_sha256: str
+ images: int
+ references: int
+ references_per_image: _Number
+
+
+class _ComparisonRow(_Artefact):
+ run_id: str
+ kind: str
+ model_id: str
+ backend: str | None
+ captioner: str | None
+ hub_repo: str | None
+ revision: str | None
+ weights_path: str
+ decode_strategy: str
+ decode_settings: dict[str, Any]
+ n_samples: int
+ metrics: dict[str, _Number | None]
+ metric_errors: dict[str, str]
+
+
+class _Comparison(_Artefact):
+ protocol: str | None
+ normalisation: str | None
+ slice: _ComparisonSlice
+ caveat: str
+ metric_keys: list[str]
+ rows: list[_ComparisonRow]
+
+
+class _LatencySlice(_Artefact):
+ source: str
+ fingerprint_sha256: str
+ images: int
+ references: int
+
+
+class _LatencyInputs(_Artefact):
+ slice: _LatencySlice
+ images: list[str]
+
+
+class _LatencySettings(_Artefact):
+ num_images: int
+ batch_sizes: list[int]
+ warmup_passes: int
+ measured_passes: int
+
+
+class _Timing(_Artefact):
+ clock: str
+ sample: str
+ load: str
+
+
+class _Summary(_Artefact):
+ count: int
+ mean: _Number
+ median: _Number
+ min: _Number
+ max: _Number
+
+
+class _Batch(_Artefact):
+ batch_size: int
+ calls_per_pass: int
+ samples_seconds: list[_Number]
+ summary_seconds: _Summary
+
+
+class _Runtime(_Artefact):
+ python: str
+ platform: str
+ packages: dict[str, str | None]
+ tensorflow_gpus: list[str] | None
+
+
+class _Latency(_Artefact):
+ protocol: str
+ model_id: str
+ backend: str
+ captioner: str
+ hub_repo: str | None
+ revision: str | None
+ decode_strategy: str
+ decode_settings: dict[str, Any]
+ device: str
+ environment: str
+ inputs: _LatencyInputs
+ settings: _LatencySettings
+ timing: _Timing
+ load_seconds: _Number
+ batches: list[_Batch]
+ seed: int
+ runtime: _Runtime
+
+
+_ModelT = TypeVar("_ModelT", bound=BaseModel)
+
+
+def find_latency_runs(results_root: str | Path, prefix: str = DEFAULT_LATENCY_PREFIX) -> list[Path]:
+ """Return every ``/*/`` latency run directory, sorted by name."""
+ return sorted(p for p in Path(results_root).glob(f"{prefix}*") if p.is_dir())
+
+
+def build_dashboard_data(
+ results_root: str | Path,
+ *,
+ comparison_id: str = DEFAULT_COMPARISON_ID,
+ latency_prefix: str = DEFAULT_LATENCY_PREFIX,
+) -> dict[str, Any]:
+ """Check the committed Phase 3 results and return the dashboard data.
+
+ Args:
+ results_root: The ``results/`` directory.
+ comparison_id: The quality summary's directory under ``results_root``.
+ latency_prefix: Every directory under ``results_root`` whose name starts
+ with this is read as a latency run.
+
+ Raises:
+ DashboardExportError: If a source is missing, malformed or inconsistent.
+ """
+ results_root = Path(results_root)
+ comparison = _read(results_root / comparison_id / "comparison.json", _Comparison, comparison_id)
+ if comparison.metric_keys != list(METRIC_KEYS):
+ raise DashboardExportError(
+ f"{comparison_id}: metric_keys {comparison.metric_keys} differ from {list(METRIC_KEYS)}"
+ )
+ latency_dirs = find_latency_runs(results_root, latency_prefix)
+ if not latency_dirs:
+ raise DashboardExportError(
+ f"no latency runs found: no {latency_prefix}* directory under {results_root.as_posix()}"
+ )
+ runs = [(d.name, _read(d / "latency.json", _Latency, d.name)) for d in latency_dirs]
+ base_id, base = runs[0]
+ for run_id, run in runs:
+ _check_latency_run(run_id, run, latency_prefix)
+ for label, value, expected in (
+ ("protocol", run.protocol, base.protocol),
+ ("inputs", run.inputs, base.inputs),
+ ("settings", run.settings, base.settings),
+ ("timing", run.timing, base.timing),
+ ("seed", run.seed, base.seed),
+ ):
+ if value != expected:
+ raise DashboardExportError(f"{run_id}: {label} doesn't match {base_id}")
+ latency_slice = base.inputs.slice
+ for label, value, expected in (
+ (
+ "slice fingerprint",
+ latency_slice.fingerprint_sha256,
+ comparison.slice.fingerprint_sha256,
+ ),
+ ("slice image count", latency_slice.images, comparison.slice.images),
+ ("slice reference count", latency_slice.references, comparison.slice.references),
+ ):
+ if value != expected:
+ raise DashboardExportError(
+ f"{base_id}: {label} {value} differs from {comparison_id} ({expected})"
+ )
+ for run_id in [row.run_id for row in comparison.rows]:
+ if not (results_root / run_id).is_dir():
+ raise DashboardExportError(
+ f"{comparison_id}: source run {run_id} has no directory under "
+ f"{results_root.as_posix()}"
+ )
+
+ model_ids = sorted({row.model_id for row in comparison.rows} | {r.model_id for _, r in runs})
+ unnamed = [model_id for model_id in model_ids if model_id not in DISPLAY_NAMES]
+ if unnamed:
+ raise DashboardExportError(
+ f"no display name for model(s) {unnamed}; add it to DISPLAY_NAMES"
+ )
+
+ s = comparison.slice
+ return {
+ "schema_version": DASHBOARD_SCHEMA_VERSION,
+ "generated_by": EXPORT_COMMAND,
+ "slice": {
+ "description": (
+ f"{s.images} COCO train2017 images, in the order of {latency_slice.source}, each "
+ f"scored against its stored references: {s.references} in total, about "
+ f"{s.references_per_image:.2f} per image. The latency runs time the first "
+ f"{base.settings.num_images} of these images."
+ ),
+ "source": latency_slice.source,
+ "fingerprint_sha256": s.fingerprint_sha256,
+ "images": s.images,
+ "references": s.references,
+ "references_per_image": s.references_per_image,
+ },
+ "overlap_caveat": comparison.caveat,
+ "quality": {
+ "protocol": comparison.protocol,
+ "normalisation": comparison.normalisation,
+ "summary_run_id": comparison_id,
+ "metrics": [
+ {"key": key, "label": label}
+ for key, label in zip(METRIC_KEYS, METRIC_LABELS, strict=True)
+ ],
+ "notes": [note.format(rpi=s.references_per_image) for note in QUALITY_NOTES],
+ },
+ "latency": {
+ "protocol": base.protocol,
+ "unit": "seconds per call; one call captions one batch",
+ "statistics": list(_Summary.model_fields),
+ "settings": base.settings.model_dump(),
+ "timing": base.timing.model_dump(),
+ "notes": list(LATENCY_NOTES),
+ },
+ "models": [_model_entry(model_id, comparison, runs) for model_id in model_ids],
+ }
+
+
+def render_dashboard_json(data: dict[str, Any]) -> str:
+ """Serialise :func:`build_dashboard_data` output exactly as it is committed."""
+ return json.dumps(data, indent=2, ensure_ascii=False) + "\n"
+
+
+def _check_latency_run(run_id: str, run: _Latency, prefix: str) -> None:
+ expected_id = f"{prefix}{run.model_id}-{run.decode_strategy}-{run.device}"
+ if run_id != expected_id:
+ raise DashboardExportError(
+ f"{run_id}: latency.json describes {expected_id} (model, decoding and device)"
+ )
+ if run.captioner not in BATCH_MODES:
+ raise DashboardExportError(f"{run_id}: unknown captioner {run.captioner!r}")
+ batch_sizes = [batch.batch_size for batch in run.batches]
+ if batch_sizes != run.settings.batch_sizes:
+ raise DashboardExportError(
+ f"{run_id}: batches {batch_sizes} differ from settings.batch_sizes "
+ f"{run.settings.batch_sizes}"
+ )
+ for batch in run.batches:
+ expected_count = batch.calls_per_pass * run.settings.measured_passes
+ if len(batch.samples_seconds) != expected_count:
+ raise DashboardExportError(
+ f"{run_id}: batch size {batch.batch_size} has {len(batch.samples_seconds)} "
+ f"samples, expected {expected_count}"
+ )
+ if summarize(batch.samples_seconds) != batch.summary_seconds.model_dump():
+ raise DashboardExportError(
+ f"{run_id}: batch size {batch.batch_size} summary_seconds doesn't match its "
+ "samples_seconds"
+ )
+
+
+def _model_entry(
+ model_id: str, comparison: _Comparison, runs: Sequence[tuple[str, _Latency]]
+) -> dict[str, Any]:
+ rows = [row for row in comparison.rows if row.model_id == model_id]
+ latency = sorted(
+ ((run_id, run) for run_id, run in runs if run.model_id == model_id),
+ key=lambda item: (item[1].device, item[1].decode_strategy, item[0]),
+ )
+ identity = {
+ field: _agreed(
+ model_id,
+ field,
+ [(row.run_id, getattr(row, field)) for row in rows]
+ + [(run_id, getattr(run, field)) for run_id, run in latency],
+ )
+ for field in ("backend", "hub_repo", "revision")
+ }
+ quality = [
+ {
+ "run_id": row.run_id,
+ "kind": row.kind,
+ "revision": row.revision,
+ "decode_strategy": row.decode_strategy,
+ "decode_settings": row.decode_settings,
+ "n_samples": row.n_samples,
+ "metrics": row.metrics,
+ "metric_errors": row.metric_errors,
+ }
+ for row in rows
+ ]
+ latency_entries = [
+ {
+ "run_id": run_id,
+ "device": run.device,
+ "environment": run.environment,
+ "decode_strategy": run.decode_strategy,
+ "batch_mode": BATCH_MODES[run.captioner],
+ "load_seconds": run.load_seconds,
+ "batches": [
+ {
+ "batch_size": batch.batch_size,
+ "calls_per_pass": batch.calls_per_pass,
+ "summary_seconds": batch.summary_seconds.model_dump(),
+ }
+ for batch in run.batches
+ ],
+ }
+ for run_id, run in latency
+ ]
+ return {
+ "model_id": model_id,
+ "display_name": DISPLAY_NAMES[model_id],
+ **identity,
+ "source_run_ids": [entry["run_id"] for entry in quality + latency_entries],
+ "quality": quality,
+ "latency": latency_entries,
+ }
+
+
+def _agreed(model_id: str, field: str, values: list[tuple[str, str | None]]) -> str:
+ """Return the one value every run that records ``field`` gives for ``model_id``."""
+ recorded = {value for _, value in values if value is not None}
+ if not recorded:
+ raise DashboardExportError(f"{model_id}: no run records its {field}")
+ if len(recorded) > 1:
+ detail = ", ".join(f"{run_id}={value}" for run_id, value in values if value is not None)
+ raise DashboardExportError(f"{model_id}: runs disagree on {field}: {detail}")
+ return recorded.pop()
+
+
+def _read(path: Path, model: type[_ModelT], run_id: str) -> _ModelT:
+ if not path.is_file():
+ raise DashboardExportError(f"{run_id}: missing {path.name}")
+ try:
+ return model.model_validate(json.loads(path.read_text(encoding="utf-8")))
+ except (ValueError, ValidationError) as exc:
+ detail = str(exc).splitlines()[0] if str(exc) else type(exc).__name__
+ raise DashboardExportError(f"{run_id}: {path.name} is malformed: {detail}") from exc
diff --git a/src/captioning/evaluation/inspection.py b/src/captioning/evaluation/inspection.py
new file mode 100644
index 0000000000000000000000000000000000000000..aea74beca3658d89347d75c3a662074a8c1db80e
--- /dev/null
+++ b/src/captioning/evaluation/inspection.py
@@ -0,0 +1,163 @@
+"""Per-sample inspection utilities for diagnosing weak captions.
+
+The aggregate corpus metric tells you *how bad* the model is; this module
+tells you *why*. For each (image, prediction, reference-set) triple it
+records per-sample BLEU-4, sentence-level ROUGE-L, the prediction length,
+the longest repeated token run, and whether the prediction is empty after
+stripping sentinels.
+
+Three failure modes the evaluation pass is trying to surface:
+ * **Generic captions** — high BLEU-1, low BLEU-4 (n-gram trickle out).
+ * **Repetition** — large ``repeat_run`` value.
+ * **Early stopping** — ``length_tokens`` far below reference median.
+
+Output JSONL is intentionally flat (one line per sample) so it can be loaded
+with ``pandas.read_json(..., lines=True)`` or grep'd from the shell. The
+runner that uses this module writes one such file per evaluation pass
+alongside ``metrics.json`` for the same run.
+"""
+
+from __future__ import annotations
+
+import json
+from collections.abc import Iterable, Sequence
+from dataclasses import asdict, dataclass
+from itertools import pairwise
+from pathlib import Path
+
+from captioning.evaluation.tokenization import strip_sentinels
+
+
+@dataclass(frozen=True)
+class SampleDiagnostics:
+ """Inspectable record for one (image, prediction, reference-set) triple."""
+
+ image: str
+ prediction: str
+ references: list[str]
+ length_tokens: int
+ longest_repeat_run: int
+ sentence_bleu4: float | None
+ sentence_rouge_l: float | None
+ flags: list[str]
+
+
+def _longest_repeat_run(tokens: Sequence[str]) -> int:
+ """Return the longest run of immediately-repeated tokens.
+
+ Example: ``["a", "a", "a", "dog"]`` -> ``3``. Used to flag the classic
+ transformer-decoder collapse where the same token is emitted on every step.
+ """
+ if not tokens:
+ return 0
+ best = current = 1
+ for prev, cur in pairwise(tokens):
+ current = current + 1 if cur == prev else 1
+ best = max(best, current)
+ return best
+
+
+def _sentence_bleu4(prediction: str, references: Sequence[str]) -> float | None:
+ """Sentence-level BLEU-4 via sacrebleu's effective-order smoothing."""
+ try:
+ import sacrebleu
+ except ImportError:
+ return None
+ if not references or not prediction:
+ return None
+ scorer = sacrebleu.metrics.BLEU(effective_order=True, max_ngram_order=4)
+ return float(scorer.sentence_score(prediction, list(references)).score)
+
+
+def _sentence_rouge_l(prediction: str, references: Sequence[str]) -> float | None:
+ """Best-of-references sentence-level ROUGE-L F-measure (0-100 scale)."""
+ try:
+ from rouge_score import rouge_scorer
+ except ImportError:
+ return None
+ valid_refs = [r for r in references if r]
+ if not valid_refs or not prediction:
+ return None
+ scorer = rouge_scorer.RougeScorer(["rougeL"], use_stemmer=True)
+ best = max(scorer.score(r, prediction)["rougeL"].fmeasure for r in valid_refs)
+ return float(100.0 * best)
+
+
+def diagnose_sample(
+ image: str,
+ prediction: str,
+ references: Sequence[str],
+) -> SampleDiagnostics:
+ """Return :class:`SampleDiagnostics` for one prediction-vs-references row."""
+ pred_clean = strip_sentinels(prediction)
+ ref_clean = [strip_sentinels(r) for r in references if r]
+ tokens = pred_clean.split()
+
+ flags: list[str] = []
+ if not pred_clean:
+ flags.append("empty")
+ if len(tokens) <= 2:
+ flags.append("very_short")
+ repeat = _longest_repeat_run(tokens)
+ if repeat >= 3:
+ flags.append("repetitive")
+ if ref_clean and tokens and len(tokens) < min(len(r.split()) for r in ref_clean) // 2:
+ flags.append("under_length")
+
+ return SampleDiagnostics(
+ image=image,
+ prediction=pred_clean,
+ references=ref_clean,
+ length_tokens=len(tokens),
+ longest_repeat_run=repeat,
+ sentence_bleu4=_sentence_bleu4(pred_clean, ref_clean),
+ sentence_rouge_l=_sentence_rouge_l(pred_clean, ref_clean),
+ flags=flags,
+ )
+
+
+def diagnose_many(
+ images: Sequence[str],
+ predictions: Sequence[str],
+ references: Sequence[Sequence[str]],
+) -> list[SampleDiagnostics]:
+ """Vectorised :func:`diagnose_sample` over parallel sequences."""
+ if not (len(images) == len(predictions) == len(references)):
+ raise ValueError(
+ "images, predictions, references must be the same length: "
+ f"got {len(images)} / {len(predictions)} / {len(references)}"
+ )
+ return [
+ diagnose_sample(img, pred, refs)
+ for img, pred, refs in zip(images, predictions, references, strict=True)
+ ]
+
+
+def write_diagnostics_jsonl(
+ diagnostics: Iterable[SampleDiagnostics],
+ path: str | Path,
+) -> None:
+ """Write one JSON object per line — pandas/jq friendly.
+
+ Args:
+ diagnostics: An iterable of :class:`SampleDiagnostics` (typically the
+ output of :func:`diagnose_many`).
+ path: Destination file. Parent directory is created if needed.
+ """
+ out = Path(path)
+ out.parent.mkdir(parents=True, exist_ok=True)
+ with out.open("w", encoding="utf-8") as f:
+ for d in diagnostics:
+ f.write(json.dumps(asdict(d), ensure_ascii=False) + "\n")
+
+
+def format_diagnostic_row(d: SampleDiagnostics) -> str:
+ """Return a one-line human-readable summary — used by the CLI tail print."""
+ bleu = f"BLEU4={d.sentence_bleu4:5.1f}" if d.sentence_bleu4 is not None else "BLEU4= n/a"
+ rouge = f"R-L={d.sentence_rouge_l:5.1f}" if d.sentence_rouge_l is not None else "R-L= n/a"
+ flagstr = ",".join(d.flags) if d.flags else "-"
+ return (
+ f"{Path(d.image).name:35s} "
+ f"{bleu} {rouge} len={d.length_tokens:>2} repeat={d.longest_repeat_run:>2} "
+ f"flags={flagstr}\n pred: {d.prediction}\n ref : {d.references[0] if d.references else ''}"
+ )
diff --git a/src/captioning/evaluation/latency.py b/src/captioning/evaluation/latency.py
new file mode 100644
index 0000000000000000000000000000000000000000..54124c891c21dc2f42ddfa992fbd26a247fa5d49
--- /dev/null
+++ b/src/captioning/evaluation/latency.py
@@ -0,0 +1,210 @@
+"""Time captioning latency through the shared Phase 3 :class:`Captioner` interface.
+
+Implements the timing rules of ``docs/EVAL_METHODOLOGY.md`` § 9:
+
+- One sample is the wall-clock time of one ``Captioner.caption()`` call on one
+ batch of image paths, read from a monotonic clock. The call covers image
+ reading and decoding, preprocessing, generation, token decoding and caption
+ normalisation.
+- Loading the model is timed once, separately, and is never part of a sample.
+- For each batch size, the inputs are split into consecutive full batches in
+ input order. Warmup passes caption every batch untimed, then each measured
+ pass times every call.
+- Nothing is filtered: every measured call is a sample, and any failed call
+ ends the benchmark.
+
+Nothing here imports TensorFlow, ``torch`` or ``transformers``.
+"""
+
+from __future__ import annotations
+
+import importlib.metadata
+import platform
+import statistics
+import time
+from collections.abc import Callable, Sequence
+from dataclasses import dataclass
+from pathlib import Path
+from typing import TYPE_CHECKING
+
+if TYPE_CHECKING:
+ from captioning.baselines import Captioner
+
+Clock = Callable[[], float]
+
+LATENCY_PROTOCOL = "docs/EVAL_METHODOLOGY.md § 9"
+CLOCK_NAME = "time.perf_counter"
+# Distributions whose installed versions every latency run records.
+RUNTIME_PACKAGES = ("tensorflow", "tensorflow-cpu", "torch", "transformers")
+
+
+class LatencyBenchmarkError(RuntimeError):
+ """A timed call broke the benchmark's rules, so no result is produced."""
+
+
+@dataclass(frozen=True)
+class LatencySettings:
+ """What one latency run measures.
+
+ Attributes:
+ num_images: How many images, from the start of the slice, form the inputs.
+ batch_sizes: Batch sizes to time, unique and ascending. Each must divide
+ ``num_images``, so every call captions a full batch.
+ warmup_passes: Untimed passes over the inputs before measuring, per
+ batch size. At least one.
+ measured_passes: Timed passes over the inputs, per batch size.
+ """
+
+ num_images: int
+ batch_sizes: tuple[int, ...]
+ warmup_passes: int
+ measured_passes: int
+
+ def __post_init__(self) -> None:
+ if self.num_images < 1:
+ raise ValueError(f"num_images must be at least 1, got {self.num_images}")
+ if not self.batch_sizes:
+ raise ValueError("at least one batch size is needed")
+ if any(size < 1 for size in self.batch_sizes):
+ raise ValueError(f"batch sizes must be at least 1, got {list(self.batch_sizes)}")
+ if list(self.batch_sizes) != sorted(set(self.batch_sizes)):
+ raise ValueError(
+ f"batch sizes must be unique and ascending, got {list(self.batch_sizes)}"
+ )
+ uneven = [size for size in self.batch_sizes if self.num_images % size]
+ if uneven:
+ raise ValueError(
+ f"num_images {self.num_images} is not a multiple of batch size(s) {uneven}; "
+ "every timed call must caption a full batch"
+ )
+ if self.warmup_passes < 1:
+ raise ValueError(
+ f"at least one warmup pass is needed, got {self.warmup_passes}; "
+ "the first call must never be timed"
+ )
+ if self.measured_passes < 1:
+ raise ValueError(f"measured_passes must be at least 1, got {self.measured_passes}")
+
+ def to_dict(self) -> dict[str, object]:
+ return {
+ "num_images": self.num_images,
+ "batch_sizes": list(self.batch_sizes),
+ "warmup_passes": self.warmup_passes,
+ "measured_passes": self.measured_passes,
+ }
+
+
+@dataclass(frozen=True)
+class BatchLatency:
+ """Every timed call for one batch size, in measurement order."""
+
+ batch_size: int
+ calls_per_pass: int
+ samples: tuple[float, ...]
+
+ def to_dict(self) -> dict[str, object]:
+ return {
+ "batch_size": self.batch_size,
+ "calls_per_pass": self.calls_per_pass,
+ "samples_seconds": list(self.samples),
+ "summary_seconds": summarize(self.samples),
+ }
+
+
+def summarize(samples: Sequence[float]) -> dict[str, float | int]:
+ """Return the § 9 statistics of ``samples``: count, mean, median, min and max."""
+ if not samples:
+ raise ValueError("no samples to summarise")
+ return {
+ "count": len(samples),
+ "mean": statistics.fmean(samples),
+ "median": statistics.median(samples),
+ "min": min(samples),
+ "max": max(samples),
+ }
+
+
+def time_load(
+ factory: Callable[[], Captioner], *, clock: Clock = time.perf_counter
+) -> tuple[Captioner, float]:
+ """Build a captioner and load its weights, timing both steps together.
+
+ The CNN + Transformer loads its checkpoint when it is constructed, and the
+ Hugging Face adapters in ``load()``, so the load time covers both. It also
+ includes any framework import or Hub download those steps trigger.
+ """
+ start = clock()
+ captioner = factory()
+ captioner.load()
+ return captioner, _elapsed(start, clock())
+
+
+def measure_latency(
+ captioner: Captioner,
+ image_paths: Sequence[str | Path],
+ settings: LatencySettings,
+ *,
+ clock: Clock = time.perf_counter,
+) -> list[BatchLatency]:
+ """Time ``captioner`` on ``image_paths`` at every batch size in ``settings``.
+
+ Batch sizes run in ascending order. For each one, the warmup passes run
+ first and are never timed; each measured pass then times every batch, in
+ input order. Only the ``caption()`` call sits between the two clock reads.
+
+ Raises:
+ ValueError: If ``image_paths`` doesn't hold exactly ``settings.num_images``
+ paths.
+ LatencyBenchmarkError: If a call returns the wrong number of captions,
+ or the clock goes backwards.
+ Exception: Whatever a failed ``caption()`` call raises, unchanged.
+ """
+ paths = [Path(p) for p in image_paths]
+ if len(paths) != settings.num_images:
+ raise ValueError(f"expected {settings.num_images} images, got {len(paths)}")
+
+ results: list[BatchLatency] = []
+ for batch_size in settings.batch_sizes:
+ batches = [paths[i : i + batch_size] for i in range(0, len(paths), batch_size)]
+ for _ in range(settings.warmup_passes):
+ for batch in batches:
+ _check_captions(captioner, batch, captioner.caption(batch))
+ samples: list[float] = []
+ for _ in range(settings.measured_passes):
+ for batch in batches:
+ start = clock()
+ captions = captioner.caption(batch)
+ end = clock()
+ _check_captions(captioner, batch, captions)
+ samples.append(_elapsed(start, end))
+ results.append(BatchLatency(batch_size, len(batches), tuple(samples)))
+ return results
+
+
+def runtime_info() -> dict[str, object]:
+ """Python, platform and installed framework versions (``None`` if not installed)."""
+ return {
+ "python": platform.python_version(),
+ "platform": platform.platform(),
+ "packages": {name: _installed_version(name) for name in RUNTIME_PACKAGES},
+ }
+
+
+def _installed_version(distribution: str) -> str | None:
+ try:
+ return importlib.metadata.version(distribution)
+ except importlib.metadata.PackageNotFoundError:
+ return None
+
+
+def _check_captions(captioner: Captioner, batch: list[Path], captions: Sequence[str]) -> None:
+ if len(captions) != len(batch):
+ raise LatencyBenchmarkError(
+ f"{captioner.identity.model_id}: {len(captions)} captions for {len(batch)} images"
+ )
+
+
+def _elapsed(start: float, end: float) -> float:
+ if end < start:
+ raise LatencyBenchmarkError(f"the clock went backwards ({start} -> {end})")
+ return end - start
diff --git a/src/captioning/evaluation/meteor.py b/src/captioning/evaluation/meteor.py
new file mode 100644
index 0000000000000000000000000000000000000000..aa9d24c4c7678c7b4454453423adadd63af22a3e
--- /dev/null
+++ b/src/captioning/evaluation/meteor.py
@@ -0,0 +1,77 @@
+"""METEOR (Metric for Evaluation of Translation with Explicit Ordering).
+
+METEOR is part of the standard COCO captioning report alongside BLEU, ROUGE-L,
+and CIDEr. It complements BLEU by rewarding semantic matches (synonyms,
+stems) rather than only surface n-gram overlap.
+
+Implementation notes:
+ * We use the ``pycocoevalcap`` METEOR adapter, which shells out to the
+ original Java implementation. METEOR therefore needs a JRE on PATH at
+ runtime; the import succeeds either way, the Java process is spawned
+ lazily on first scoring call.
+ * METEOR's process is long-lived and accepts batches over stdin/stdout —
+ a single ``compute_score`` call handles the whole corpus in one round
+ trip, so this scales to thousands of examples without thrashing the JVM.
+"""
+
+from __future__ import annotations
+
+from collections.abc import Sequence
+
+from captioning.evaluation.tokenization import (
+ strip_sentinels_many,
+ strip_sentinels_references,
+)
+
+
+def corpus_meteor_score(
+ predictions: Sequence[str],
+ references: Sequence[Sequence[str]],
+) -> float:
+ """Compute corpus METEOR via ``pycocoevalcap``.
+
+ Args:
+ predictions: One generated caption per example.
+ references: One *list* of reference captions per example.
+
+ Returns:
+ Corpus METEOR in the 0-100 range to match the rest of this package.
+ pycocoevalcap returns 0-1; we multiply by 100 for report parity.
+
+ Raises:
+ ImportError: If ``pycocoevalcap`` is not installed.
+ ValueError: On mismatched lengths.
+ RuntimeError: If the Java METEOR process cannot be launched.
+ """
+ if len(predictions) != len(references):
+ raise ValueError(
+ f"predictions ({len(predictions)}) and references "
+ f"({len(references)}) must have the same length"
+ )
+ if not predictions:
+ return 0.0
+
+ try:
+ from pycocoevalcap.meteor.meteor import Meteor
+ except ImportError as e:
+ raise ImportError(
+ "pycocoevalcap is required for METEOR evaluation. "
+ "Install via `pip install -r requirements-eval.txt`."
+ ) from e
+
+ preds = strip_sentinels_many(predictions)
+ refs = strip_sentinels_references(references)
+
+ gts = {str(i): [r for r in ref_list if r] for i, ref_list in enumerate(refs)}
+ res = {str(i): [p] for i, p in enumerate(preds)}
+
+ scorer = Meteor()
+ try:
+ score, _ = scorer.compute_score(gts, res)
+ except Exception as e: # — meteor.py raises bare Exceptions
+ raise RuntimeError(
+ "METEOR scoring failed. METEOR requires a Java runtime on PATH. "
+ f"Underlying error: {e}"
+ ) from e
+
+ return float(100.0 * score)
diff --git a/src/captioning/evaluation/rouge.py b/src/captioning/evaluation/rouge.py
new file mode 100644
index 0000000000000000000000000000000000000000..4aac7f5168e33386f0f312d1d9ae1fae32087a85
--- /dev/null
+++ b/src/captioning/evaluation/rouge.py
@@ -0,0 +1,75 @@
+"""Corpus ROUGE-L for caption evaluation.
+
+ROUGE-L measures the longest common subsequence between a prediction and its
+references and is part of the standard COCO captioning report (BLEU, METEOR,
+ROUGE-L, CIDEr).
+
+Implementation notes:
+ * We use Google's ``rouge_score`` package (the canonical implementation
+ since the original perl scripts were retired). It returns precision /
+ recall / fmeasure per (prediction, reference) pair.
+ * COCO captions ship up to 5 references per image. We take the maximum
+ F-measure across references — same convention as pycocoevalcap.
+ * The corpus score is the mean of per-sample F-measures, matching how
+ sacrebleu and pycocoevalcap aggregate metrics over a dataset.
+"""
+
+from __future__ import annotations
+
+from collections.abc import Sequence
+
+from captioning.evaluation.tokenization import (
+ strip_sentinels_many,
+ strip_sentinels_references,
+)
+
+
+def corpus_rouge_l_score(
+ predictions: Sequence[str],
+ references: Sequence[Sequence[str]],
+) -> float:
+ """Compute corpus ROUGE-L F-measure.
+
+ Args:
+ predictions: One generated caption per example.
+ references: One *list* of reference captions per example.
+
+ Returns:
+ Mean ROUGE-L F-measure across examples, in the 0-100 range to match
+ sacrebleu's convention (so the report shows BLEU/ROUGE/METEOR/CIDEr
+ on comparable scales).
+
+ Raises:
+ ImportError: If ``rouge_score`` is not installed
+ (``pip install -r requirements-eval.txt``).
+ ValueError: On mismatched lengths or an empty references slot.
+ """
+ if len(predictions) != len(references):
+ raise ValueError(
+ f"predictions ({len(predictions)}) and references "
+ f"({len(references)}) must have the same length"
+ )
+ if not predictions:
+ return 0.0
+
+ try:
+ from rouge_score import rouge_scorer
+ except ImportError as e:
+ raise ImportError(
+ "rouge_score is required for ROUGE-L evaluation. "
+ "Install via `pip install -r requirements-eval.txt`."
+ ) from e
+
+ scorer = rouge_scorer.RougeScorer(["rougeL"], use_stemmer=True)
+ preds = strip_sentinels_many(predictions)
+ refs = strip_sentinels_references(references)
+
+ total = 0.0
+ for hypothesis, ref_list in zip(preds, refs, strict=True):
+ valid_refs = [r for r in ref_list if r]
+ if not valid_refs or not hypothesis:
+ continue
+ best = max(scorer.score(r, hypothesis)["rougeL"].fmeasure for r in valid_refs)
+ total += best
+
+ return float(100.0 * total / len(preds))
diff --git a/src/captioning/evaluation/runner.py b/src/captioning/evaluation/runner.py
new file mode 100644
index 0000000000000000000000000000000000000000..6d6c53bc8729d3b06a32beaf9bac45ba39031989
--- /dev/null
+++ b/src/captioning/evaluation/runner.py
@@ -0,0 +1,128 @@
+"""Single entry point that returns every implemented caption-quality metric.
+
+``compute_all_metrics`` is the shared aggregator used by the CLI
+(:mod:`scripts.evaluate`) and the per-sample inspection utility. It produces
+a single :class:`MetricsReport` so downstream code never has to know which
+metrics exist in the package — only how to read fields off the dataclass.
+
+Adding a new metric is the four-step pattern this package already follows
+elsewhere:
+ 1. Implement ``corpus__score`` in a sibling module.
+ 2. Add an entry to :class:`MetricsReport`.
+ 3. Call it from :func:`compute_all_metrics` (wrapped in a try/except so a
+ single broken metric never poisons the whole report).
+ 4. Add a unit test on a toy fixture.
+
+The exception swallowing is deliberate — METEOR needs Java, CIDEr needs
+multiple samples, sacrebleu is always available. We do NOT want one
+unavailable metric to kill the entire evaluation pass; instead we record
+``None`` for that metric and surface a per-metric ``errors`` field so callers
+(and the CLI) can flag the issue without losing the metrics that did work.
+"""
+
+from __future__ import annotations
+
+from collections.abc import Sequence
+from dataclasses import asdict, dataclass, field
+
+from captioning.evaluation.bleu import corpus_bleu_breakdown
+from captioning.evaluation.cider import MIN_SAMPLES_FOR_CIDER, corpus_cider_score
+from captioning.evaluation.meteor import corpus_meteor_score
+from captioning.evaluation.rouge import corpus_rouge_l_score
+
+
+@dataclass(frozen=True)
+class MetricsReport:
+ """Aggregate metric snapshot for one evaluation pass.
+
+ Every metric is ``float | None`` — ``None`` means the metric was skipped
+ (uninstalled, environment missing Java, too few samples for CIDEr, ...).
+ The reason for skipping is in :attr:`errors` keyed by metric name.
+ """
+
+ n_examples: int
+ bleu1: float | None = None
+ bleu2: float | None = None
+ bleu3: float | None = None
+ bleu4: float | None = None
+ rouge_l: float | None = None
+ meteor: float | None = None
+ cider: float | None = None
+ errors: dict[str, str] = field(default_factory=dict)
+
+ def to_dict(self) -> dict[str, object]:
+ """Return a JSON-serialisable dict (``errors`` becomes a sub-object)."""
+ return asdict(self)
+
+
+def compute_all_metrics(
+ predictions: Sequence[str],
+ references: Sequence[Sequence[str]],
+ *,
+ include_meteor: bool = True,
+ include_cider: bool = True,
+) -> MetricsReport:
+ """Compute every available metric on a single ``(preds, refs)`` corpus.
+
+ Args:
+ predictions: One generated caption per example.
+ references: One *list* of reference captions per example.
+ include_meteor: Set False to skip METEOR (avoids the JVM spawn —
+ helpful in CI where Java isn't installed).
+ include_cider: Set False to skip CIDEr (avoids the warning when
+ running on tiny corpora; the runner also auto-skips below
+ ``MIN_SAMPLES_FOR_CIDER``).
+
+ Returns:
+ A :class:`MetricsReport` with every field populated by a corpus
+ metric or recorded as failed in ``errors``.
+ """
+ if len(predictions) != len(references):
+ raise ValueError(
+ f"predictions ({len(predictions)}) and references "
+ f"({len(references)}) must have the same length"
+ )
+
+ errors: dict[str, str] = {}
+ bleu1 = bleu2 = bleu3 = bleu4 = None
+ rouge_l = meteor = cider = None
+
+ try:
+ bleu = corpus_bleu_breakdown(predictions, references)
+ bleu1, bleu2, bleu3, bleu4 = bleu.bleu1, bleu.bleu2, bleu.bleu3, bleu.bleu4
+ except Exception as e: # — surface, don't crash the run
+ errors["bleu"] = repr(e)
+
+ try:
+ rouge_l = corpus_rouge_l_score(predictions, references)
+ except Exception as e:
+ errors["rouge_l"] = repr(e)
+
+ if include_meteor:
+ try:
+ meteor = corpus_meteor_score(predictions, references)
+ except Exception as e:
+ errors["meteor"] = repr(e)
+
+ if include_cider:
+ if len(predictions) < MIN_SAMPLES_FOR_CIDER:
+ errors["cider"] = (
+ f"skipped: needs >= {MIN_SAMPLES_FOR_CIDER} examples, " f"got {len(predictions)}"
+ )
+ else:
+ try:
+ cider = corpus_cider_score(predictions, references)
+ except Exception as e:
+ errors["cider"] = repr(e)
+
+ return MetricsReport(
+ n_examples=len(predictions),
+ bleu1=bleu1,
+ bleu2=bleu2,
+ bleu3=bleu3,
+ bleu4=bleu4,
+ rouge_l=rouge_l,
+ meteor=meteor,
+ cider=cider,
+ errors=errors,
+ )
diff --git a/src/captioning/evaluation/slice.py b/src/captioning/evaluation/slice.py
new file mode 100644
index 0000000000000000000000000000000000000000..e01d0eae3307cf702e0a4d9ae6a8f16479eaacb6
--- /dev/null
+++ b/src/captioning/evaluation/slice.py
@@ -0,0 +1,93 @@
+"""Load the Phase 3 evaluation slice from a committed run.
+
+Phase 3 scores every model on the exact images and references of an existing
+run instead of re-sampling COCO (``docs/EVAL_METHODOLOGY.md`` § 8.2). A run's
+``predictions.jsonl`` already records that slice: one row per image, in
+evaluation order, with the references its metrics were computed against.
+
+The stored image paths belong to the machine that produced the run (Kaggle for
+the committed runs), so each one is remapped by file name onto a local images
+directory. Nothing else is transformed: row order, reference order and
+reference text are kept exactly. Image files don't need to exist here; the
+runner checks them before any model loads.
+"""
+
+from __future__ import annotations
+
+import hashlib
+import json
+from dataclasses import dataclass, field
+from pathlib import Path
+
+
+@dataclass(frozen=True)
+class EvalSlice:
+ """The images and stored references of one committed evaluation run.
+
+ Two slices compare equal when their image paths and references match,
+ whichever ``predictions.jsonl`` they were read from.
+ """
+
+ source: Path = field(compare=False)
+ image_paths: tuple[Path, ...]
+ references: tuple[tuple[str, ...], ...]
+
+ def __len__(self) -> int:
+ return len(self.image_paths)
+
+
+def load_eval_slice(predictions_path: str | Path, images_dir: str | Path) -> EvalSlice:
+ """Read the slice recorded in a run's ``predictions.jsonl``.
+
+ Args:
+ predictions_path: A committed ``results//predictions.jsonl``.
+ images_dir: Local directory holding the slice images. Each stored image
+ path is replaced by ``images_dir / ``.
+
+ Returns:
+ The slice, in file order, with references exactly as stored.
+
+ Raises:
+ ValueError: If a row lacks a non-empty ``image`` string or a non-empty
+ list of reference strings. The message names the file and line.
+ """
+ source = Path(predictions_path)
+ root = Path(images_dir)
+ image_paths: list[Path] = []
+ references: list[tuple[str, ...]] = []
+
+ with source.open(encoding="utf-8") as f:
+ for lineno, line in enumerate(f, start=1):
+ if not line.strip():
+ continue
+ row = json.loads(line)
+ image = row.get("image") if isinstance(row, dict) else None
+ refs = row.get("references") if isinstance(row, dict) else None
+ name = _file_name(image) if isinstance(image, str) else ""
+ if not name:
+ raise ValueError(f"{source}:{lineno}: row has no image file name")
+ if not (isinstance(refs, list) and refs and all(isinstance(r, str) for r in refs)):
+ raise ValueError(f"{source}:{lineno}: row needs a non-empty list of references")
+ image_paths.append(root / name)
+ references.append(tuple(refs))
+
+ return EvalSlice(source=source, image_paths=tuple(image_paths), references=tuple(references))
+
+
+def slice_fingerprint(eval_slice: EvalSlice) -> str:
+ """SHA-256 of the slice's image file names and references, in order.
+
+ Hashes the parsed content rather than the file bytes, so line endings and
+ the machine-specific image directory don't change the identity.
+ """
+ payload = [
+ [path.name, list(refs)]
+ for path, refs in zip(eval_slice.image_paths, eval_slice.references, strict=True)
+ ]
+ encoded = json.dumps(payload, ensure_ascii=False, separators=(",", ":")).encode("utf-8")
+ return hashlib.sha256(encoded).hexdigest()
+
+
+def _file_name(stored_path: str) -> str:
+ """Return the file name of a stored path written with either separator."""
+ return stored_path.replace("\\", "/").rsplit("/", 1)[-1]
diff --git a/src/captioning/evaluation/tokenization.py b/src/captioning/evaluation/tokenization.py
new file mode 100644
index 0000000000000000000000000000000000000000..9e3b387b1062ba105b2b05291174a9c9680527b2
--- /dev/null
+++ b/src/captioning/evaluation/tokenization.py
@@ -0,0 +1,44 @@
+"""Reference/hypothesis tokenisation helpers shared across metric modules.
+
+CIDEr, METEOR (via pycocoevalcap) and ROUGE-L all expect *string* inputs but
+each implements its own tokenisation internally. To compare metrics on the
+same footing we strip our sentinel tokens once, up front, before any metric
+sees a caption.
+
+These helpers exist because every metric module would otherwise re-implement
+the same ``[start]`` / ``[end]`` stripping inline — and bugs would diverge.
+"""
+
+from __future__ import annotations
+
+from collections.abc import Iterable, Sequence
+
+from captioning.preprocessing.caption import END_TOKEN, START_TOKEN
+
+
+def strip_sentinels(caption: str) -> str:
+ """Remove ``[start]`` / ``[end]`` sentinels and collapse whitespace.
+
+ Args:
+ caption: A caption string that may carry our training sentinels.
+
+ Returns:
+ The same caption with the sentinels removed and consecutive whitespace
+ collapsed to a single space. Empty input returns ``""``.
+ """
+ if not caption:
+ return ""
+ cleaned = caption.replace(START_TOKEN, " ").replace(END_TOKEN, " ")
+ return " ".join(cleaned.split())
+
+
+def strip_sentinels_many(captions: Iterable[str]) -> list[str]:
+ """Apply :func:`strip_sentinels` to every caption in ``captions``."""
+ return [strip_sentinels(c) for c in captions]
+
+
+def strip_sentinels_references(
+ references: Sequence[Sequence[str]],
+) -> list[list[str]]:
+ """Apply :func:`strip_sentinels` to every reference list."""
+ return [strip_sentinels_many(refs) for refs in references]
diff --git a/src/captioning/inference/__init__.py b/src/captioning/inference/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..9fa9ff3e567be37d3c378a91c06c117e79488a53
--- /dev/null
+++ b/src/captioning/inference/__init__.py
@@ -0,0 +1,23 @@
+"""Inference — generation algorithms and the FastAPI-friendly ``CaptionPredictor``.
+
+The notebook generates captions through a free-floating ``generate_caption``
+function that closes over global state (``caption_model``, ``tokenizer``,
+``MAX_LENGTH``). We keep the same algorithm but inject those dependencies
+explicitly so it works inside a long-lived process (FastAPI lifespan).
+
+ image_loader.py ``load_image_from_path`` — used at request time
+ greedy.py ``generate_caption_greedy`` — the notebook's argmax decode loop
+ predictor.py ``CaptionPredictor`` — singleton wrapper for the API
+"""
+
+from captioning.inference.beam import generate_caption_beam
+from captioning.inference.greedy import generate_caption_greedy
+from captioning.inference.image_loader import load_image_from_path
+from captioning.inference.predictor import CaptionPredictor
+
+__all__ = [
+ "CaptionPredictor",
+ "generate_caption_beam",
+ "generate_caption_greedy",
+ "load_image_from_path",
+]
diff --git a/src/captioning/inference/beam.py b/src/captioning/inference/beam.py
new file mode 100644
index 0000000000000000000000000000000000000000..7493651b052c2b13449bea2251473aeeec2154aa
--- /dev/null
+++ b/src/captioning/inference/beam.py
@@ -0,0 +1,240 @@
+"""Beam-search caption generation.
+
+Greedy decoding (the only Phase 1 option) routinely produces generic captions
+because the model's most-likely-next-token at every step rarely lines up with
+the most-likely-*sequence*. Beam search explores multiple partial captions in
+parallel and ranks them by total log-probability, lifting BLEU-4 by 2-5
+points on most transformer captioners without retraining.
+
+Algorithm (standard beam search with length and repetition controls):
+ * Maintain ``beam_width`` active beams, each a (token-id sequence, score).
+ * At each step, batch every active beam through the decoder once, take the
+ log-softmax at the current position, apply the repetition penalty and
+ the optional no-repeat-ngram block, and pick the global top-K
+ candidates across (beam, vocab) pairs.
+ * Beams that emit ``[end]`` move into the finished list (their score is
+ already final at that point); the search ends when ``beam_width`` beams
+ have finished or we hit the max-length budget.
+ * Final ranking divides each finished beam's score by
+ ``len(seq) ** length_penalty`` so the search isn't biased toward very
+ short sequences (the classic length problem in beam search).
+
+This implementation is intentionally kept *callable* — the same predictor
+class dispatches between :func:`generate_caption_greedy` and this one based
+on ``decode_strategy``. Phase 3 model wrappers (BLIP, ViT-GPT2) can reuse
+the same dispatcher.
+"""
+
+from __future__ import annotations
+
+import math
+from dataclasses import dataclass, field
+
+from captioning.preprocessing.caption import END_TOKEN, START_TOKEN
+from captioning.preprocessing.tokenizer import CaptionTokenizer
+
+_LOG_EPSILON = 1e-12
+
+
+@dataclass
+class _Beam:
+ """One partial caption under exploration."""
+
+ token_ids: list[int]
+ score: float
+ finished: bool = False
+ history: set[int] = field(default_factory=set)
+
+ def length(self) -> int:
+ """Number of generated tokens (excludes the seed [start] token)."""
+ return max(len(self.token_ids) - 1, 1)
+
+
+def _apply_repetition_penalty(
+ log_probs,
+ history_ids: set[int],
+ penalty: float,
+):
+ """Subtract ``log(penalty)`` from already-seen tokens' log-probabilities.
+
+ HuggingFace's repetition_penalty (Keskar et al. 2019) divides logits by
+ ``penalty`` (>1) for tokens already in the context. We work with log-
+ probabilities here, so the equivalent operation is to *subtract*
+ ``log(penalty)`` for positive log-probabilities and add it for negative
+ ones — but log-probabilities are always non-positive, so we always make
+ seen tokens less likely. That is the correct direction (we want to
+ discourage repetition).
+ """
+ if penalty <= 1.0 or not history_ids:
+ return log_probs
+ log_pen = math.log(penalty)
+ for tid in history_ids:
+ if 0 <= tid < log_probs.shape[-1]:
+ log_probs[tid] -= log_pen
+ return log_probs
+
+
+def _blocks_repeat_ngram(seq: list[int], candidate: int, n: int) -> bool:
+ """Return True if appending ``candidate`` would repeat an n-gram in ``seq``."""
+ if n <= 0 or len(seq) < n - 1:
+ return False
+ tail = tuple(seq[-(n - 1) :] + [candidate]) if n > 1 else (candidate,)
+ return any(tuple(seq[i : i + n]) == tail for i in range(len(seq) - n + 1))
+
+
+def generate_caption_beam( # — beam search has many knobs by nature
+ model,
+ tokenizer: CaptionTokenizer,
+ image_tensor,
+ max_length: int,
+ *,
+ beam_width: int = 3,
+ length_penalty: float = 1.0,
+ repetition_penalty: float = 1.0,
+ no_repeat_ngram_size: int = 0,
+) -> str:
+ """Generate a caption using beam search with optional length / repetition control.
+
+ Args:
+ model: An ``ImageCaptioningModel`` whose weights have been loaded.
+ tokenizer: Fitted :class:`CaptionTokenizer`.
+ image_tensor: ``[299, 299, 3]`` float tensor as produced by
+ ``inference.load_image_from_path``.
+ max_length: Same budget as greedy (``config.model.max_length``); the
+ search stops at the first of (all beams finished, length exhausted).
+ beam_width: Number of parallel hypotheses. ``1`` reduces to greedy.
+ length_penalty: GNMT-style penalty exponent. ``score / len ** alpha``.
+ ``0.0`` disables it; ``0.6-1.0`` is the common range. Higher values
+ favour longer captions.
+ repetition_penalty: HuggingFace's CTRL-style penalty. ``1.0`` disables
+ it; ``>1.0`` penalises tokens already in the partial caption.
+ no_repeat_ngram_size: If ``> 0``, forbids emitting any token that
+ would complete an n-gram already present in the partial caption.
+ ``3`` is a common choice for captioning.
+
+ Returns:
+ The best-scoring caption (sentinels stripped, same convention as
+ :func:`generate_caption_greedy`).
+ """
+ import numpy as np
+ import tensorflow as tf
+
+ # 1. Encode the image once. Beams share the encoded features.
+ img = tf.expand_dims(image_tensor, axis=0)
+ img_embed = model.cnn_model(img)
+ img_encoded = model.encoder(img_embed, training=False)
+
+ start_id = tokenizer.word_to_id(START_TOKEN)
+ end_id = tokenizer.word_to_id(END_TOKEN)
+
+ # 2. Initialise a single seed beam containing only the [start] token.
+ beams: list[_Beam] = [_Beam(token_ids=[start_id], score=0.0, history={start_id})]
+ finished: list[_Beam] = []
+
+ decode_steps = max_length - 1 # decoder is fed sequences of length max_length-1
+
+ for step in range(decode_steps):
+ if not beams:
+ break
+
+ # 3. Batch every active beam into a single decoder forward pass.
+ token_batch = np.zeros((len(beams), decode_steps), dtype=np.int64)
+ for i, beam in enumerate(beams):
+ seq = beam.token_ids[:decode_steps]
+ token_batch[i, : len(seq)] = seq
+
+ token_tensor = tf.convert_to_tensor(token_batch)
+ mask = tf.cast(token_tensor != 0, tf.int32)
+ # Encoded features must be broadcast to match the beam batch dimension.
+ encoded_batch = tf.repeat(img_encoded, repeats=len(beams), axis=0)
+ preds = model.decoder(token_tensor, encoded_batch, training=False, mask=mask)
+ # preds is [B, T, V]; we read position `step` for each beam.
+ step_probs = preds.numpy()[:, step, :]
+ step_log_probs = np.log(step_probs + _LOG_EPSILON)
+
+ # 4. Expand every beam, then keep the global top-K.
+ candidates: list[_Beam] = []
+ vocab_size = step_log_probs.shape[-1]
+ for i, beam in enumerate(beams):
+ lp = step_log_probs[i].copy()
+ lp = _apply_repetition_penalty(lp, beam.history, repetition_penalty)
+
+ # Pick a wider candidate pool than beam_width per beam — when most
+ # beams want the same token, expansion needs slack to remain diverse.
+ pool = min(beam_width * 2, vocab_size)
+ top_ids = np.argpartition(-lp, pool - 1)[:pool]
+ top_ids = top_ids[np.argsort(-lp[top_ids])]
+
+ for tid in top_ids:
+ tid_int = int(tid)
+ if no_repeat_ngram_size > 0 and _blocks_repeat_ngram(
+ beam.token_ids, tid_int, no_repeat_ngram_size
+ ):
+ continue
+ new_seq = [*beam.token_ids, tid_int]
+ new_score = beam.score + float(lp[tid_int])
+ new_history = beam.history | {tid_int}
+ candidates.append(
+ _Beam(
+ token_ids=new_seq,
+ score=new_score,
+ finished=(tid_int == end_id),
+ history=new_history,
+ )
+ )
+
+ # 5. Sort candidates by score and keep the top ``beam_width`` actives.
+ candidates.sort(key=lambda b: b.score, reverse=True)
+ next_beams: list[_Beam] = []
+ for cand in candidates:
+ if cand.finished:
+ finished.append(cand)
+ continue
+ next_beams.append(cand)
+ if len(next_beams) >= beam_width:
+ break
+ beams = next_beams
+
+ # 6. Early termination — we already have enough finished beams and
+ # none of the active ones can beat the best finished score (their
+ # best-case future log-prob is 0, so length-normalised score won't
+ # beat the current top).
+ if len(finished) >= beam_width and beams:
+ best_finished = max(_length_normalised(b, length_penalty) for b in finished)
+ best_active_upper_bound = max(_length_normalised(b, length_penalty) for b in beams)
+ if best_active_upper_bound <= best_finished:
+ break
+
+ # 7. Anything still active at the budget cap counts as finished.
+ finished.extend(beams)
+ if not finished:
+ return ""
+
+ finished.sort(key=lambda b: _length_normalised(b, length_penalty), reverse=True)
+ best = finished[0]
+ return _detokenize(best.token_ids, tokenizer, end_id)
+
+
+def _length_normalised(beam: _Beam, alpha: float) -> float:
+ """Apply length penalty to a beam score (higher == better)."""
+ if alpha == 0.0:
+ return beam.score
+ return beam.score / (beam.length() ** alpha)
+
+
+def _detokenize(
+ token_ids: list[int],
+ tokenizer: CaptionTokenizer,
+ end_id: int,
+) -> str:
+ """Convert beam token ids back to a clean caption string."""
+ words: list[str] = []
+ for tid in token_ids:
+ if tid == end_id:
+ break
+ word = tokenizer.decode_id(tid)
+ # Skip [start], padding, and OOV ids that decode to empty strings.
+ if word in {"", START_TOKEN, END_TOKEN, "[UNK]"}:
+ continue
+ words.append(word)
+ return " ".join(words)
diff --git a/src/captioning/inference/greedy.py b/src/captioning/inference/greedy.py
new file mode 100644
index 0000000000000000000000000000000000000000..c8f15e1759e886761e15f8af3e77b7decb396985
--- /dev/null
+++ b/src/captioning/inference/greedy.py
@@ -0,0 +1,76 @@
+"""Greedy caption generation.
+
+Mirrors notebook cell 25's ``generate_caption`` exactly. The notebook closes
+over four globals (``caption_model``, ``tokenizer``, ``idx2word``,
+``MAX_LENGTH``); we accept them as explicit arguments so the function is
+callable from tests, scripts, FastAPI, and the parity audit.
+
+The algorithm:
+ 1. CNN-encode the image.
+ 2. Transformer-encode the patch features.
+ 3. Seed the caption with ``[start]``.
+ 4. For each position 0 ... ``max_length - 2``:
+ a. Tokenise the partial caption (``[:, :-1]`` because TextVectorization
+ pads to ``max_length`` and we feed ``max_length - 1`` positions
+ into the decoder).
+ b. Decode and take the argmax at the current position.
+ c. Stop on ``[end]``; otherwise append the predicted word.
+ 5. Strip the ``[start]`` prefix and return.
+"""
+
+from __future__ import annotations
+
+from captioning.preprocessing.caption import END_TOKEN, START_TOKEN
+from captioning.preprocessing.tokenizer import CaptionTokenizer
+
+
+def generate_caption_greedy(
+ model,
+ tokenizer: CaptionTokenizer,
+ image_tensor,
+ max_length: int,
+ *,
+ add_noise: bool = False,
+) -> str:
+ """Generate a caption for one image using greedy (argmax) decoding.
+
+ Args:
+ model: An ``ImageCaptioningModel`` whose weights have been loaded.
+ tokenizer: Fitted ``CaptionTokenizer`` (the same one used at training).
+ image_tensor: A ``[299, 299, 3]`` float tensor produced by
+ ``inference.load_image_from_path`` (or ``preprocess_image_tensor``).
+ max_length: Decode budget — equals ``config.model.max_length`` (40
+ in the notebook).
+ add_noise: Replicates the notebook's ``add_noise`` knob; off by default.
+
+ Returns:
+ The generated caption string with the ``[start]`` sentinel removed.
+ The ``[end]`` sentinel is naturally absent because the loop breaks on it.
+ """
+ import numpy as np
+ import tensorflow as tf
+
+ img = image_tensor
+ if add_noise:
+ noise = tf.random.normal(img.shape) * 0.1
+ img = img + noise
+ img = (img - tf.reduce_min(img)) / (tf.reduce_max(img) - tf.reduce_min(img))
+
+ img = tf.expand_dims(img, axis=0)
+ img_embed = model.cnn_model(img)
+ img_encoded = model.encoder(img_embed, training=False)
+
+ y_inp = START_TOKEN
+ for i in range(max_length - 1):
+ tokenized = tokenizer.encode([y_inp])[:, :-1]
+ mask = tf.cast(tokenized != 0, tf.int32)
+ pred = model.decoder(tokenized, img_encoded, training=False, mask=mask)
+
+ pred_idx = np.argmax(pred[0, i, :])
+ pred_idx = tf.convert_to_tensor(pred_idx)
+ pred_word = tokenizer.decode_id(pred_idx)
+ if pred_word == END_TOKEN:
+ break
+ y_inp += " " + pred_word
+
+ return y_inp.replace(f"{START_TOKEN} ", "")
diff --git a/src/captioning/inference/image_loader.py b/src/captioning/inference/image_loader.py
new file mode 100644
index 0000000000000000000000000000000000000000..e59a52fac8a035dd212e865f7e7d7f6339383fd3
--- /dev/null
+++ b/src/captioning/inference/image_loader.py
@@ -0,0 +1,32 @@
+"""Inference-time image loader — same path as cell 25 of the notebook.
+
+The training pipeline goes through ``data.pipeline.build_*_pipeline`` which
+calls ``preprocessing.image.preprocess_image_tensor``. The inference path
+must produce the same tensor for the same image, otherwise BLEU drops
+silently. This module re-uses ``preprocess_image_tensor`` so train/serve
+parity is by construction.
+"""
+
+from __future__ import annotations
+
+from captioning.preprocessing.image import preprocess_image_tensor
+
+
+def load_image_from_path(image_path: str):
+ """Read a JPEG/PNG from disk and produce a model-ready tensor.
+
+ Mirrors the ``load_image_from_path`` helper in notebook cell 25.
+
+ Args:
+ image_path: Filesystem path to the image. ``str``, ``Path``, and
+ ``tf.string`` tensors all work (TF does the conversion).
+
+ Returns:
+ A ``tf.Tensor`` of shape ``[299, 299, 3]``, dtype ``float32``,
+ with InceptionV3 normalisation.
+ """
+ import tensorflow as tf
+
+ raw = tf.io.read_file(image_path)
+ image = tf.io.decode_jpeg(raw, channels=3)
+ return preprocess_image_tensor(image)
diff --git a/src/captioning/inference/predictor.py b/src/captioning/inference/predictor.py
new file mode 100644
index 0000000000000000000000000000000000000000..04aa16378bb024ef51acaf2a3e9e225974239ccd
--- /dev/null
+++ b/src/captioning/inference/predictor.py
@@ -0,0 +1,221 @@
+"""``CaptionPredictor`` — stateful, FastAPI-friendly inference singleton.
+
+Why a class around the existing functions:
+ * The FastAPI lifespan loads weights once at boot and reuses the same
+ model across every request. A predictor object is the natural home for
+ "loaded model + loaded tokenizer + decoded config".
+ * Tests can construct one with stub objects without monkey-patching globals.
+ * Multiple decode strategies (greedy, beam) live behind the same
+ ``predict_tensor`` / ``predict_path`` API — callers do not need to know
+ which one is active.
+
+Construction is *not* the same as readiness: ``CaptionPredictor.warmup()``
+runs one inference on a dummy tensor so the first real request doesn't pay
+TF's lazy graph-build cost (typically 2-5 seconds).
+"""
+
+from __future__ import annotations
+
+from pathlib import Path
+from typing import Literal, get_args
+
+from captioning.config.schema import AppConfig
+from captioning.inference.beam import generate_caption_beam
+from captioning.inference.greedy import generate_caption_greedy
+from captioning.inference.image_loader import load_image_from_path
+from captioning.preprocessing.tokenizer import CaptionTokenizer
+from captioning.utils.logging import get_logger
+
+log = get_logger(__name__)
+
+DecodeStrategy = Literal["greedy", "beam"]
+DECODE_STRATEGIES: tuple[str, ...] = get_args(DecodeStrategy)
+
+
+class CaptionPredictor:
+ """Thin wrapper exposing ``predict_path`` / ``predict_tensor`` / ``warmup``."""
+
+ def __init__(
+ self,
+ model,
+ tokenizer: CaptionTokenizer,
+ config: AppConfig,
+ *,
+ decode_strategy: DecodeStrategy = "greedy",
+ beam_width: int = 3,
+ length_penalty: float = 1.0,
+ repetition_penalty: float = 1.0,
+ no_repeat_ngram_size: int = 0,
+ ) -> None:
+ """Args:
+ model: Loaded ``ImageCaptioningModel``. Caller is responsible for
+ having called ``model.load_weights(...)`` already.
+ tokenizer: Fitted ``CaptionTokenizer``.
+ config: Validated ``AppConfig`` — ``model.max_length`` is consumed.
+ decode_strategy: ``"greedy"`` (argmax per step, byte-for-byte parity
+ with the IEEE notebook) or ``"beam"`` (beam search with length
+ and repetition controls).
+ beam_width: Beam width when ``decode_strategy == "beam"``. Ignored
+ for greedy.
+ length_penalty: GNMT length penalty; ``0.0`` disables, ``0.6-1.0`` is
+ the common range.
+ repetition_penalty: HF-style multiplicative penalty on already-seen
+ tokens; ``1.0`` disables.
+ no_repeat_ngram_size: If > 0, blocks any token that would repeat an
+ n-gram already in the partial caption.
+ """
+ if decode_strategy not in DECODE_STRATEGIES:
+ raise ValueError(f"decode_strategy must be 'greedy' or 'beam', got {decode_strategy!r}")
+ if beam_width < 1:
+ raise ValueError(f"beam_width must be >= 1, got {beam_width}")
+ self.model = model
+ self.tokenizer = tokenizer
+ self.config = config
+ self.decode_strategy: DecodeStrategy = decode_strategy
+ self.beam_width = beam_width
+ self.length_penalty = length_penalty
+ self.repetition_penalty = repetition_penalty
+ self.no_repeat_ngram_size = no_repeat_ngram_size
+
+ @classmethod
+ def from_artifacts(
+ cls,
+ weights_path: str | Path,
+ tokenizer_dir: str | Path,
+ config: AppConfig,
+ *,
+ decode_strategy: DecodeStrategy | None = None,
+ beam_width: int | None = None,
+ length_penalty: float | None = None,
+ repetition_penalty: float | None = None,
+ no_repeat_ngram_size: int | None = None,
+ ) -> CaptionPredictor:
+ """Load weights and tokenizer from disk and return a ready predictor.
+
+ Decoding knobs fall back to :class:`ServeConfig` defaults when not
+ passed explicitly — keeping CLI flags overridable while still letting
+ deploy-time YAML drive the production behaviour.
+ """
+ from captioning.models.factory import build_caption_model
+
+ tokenizer = CaptionTokenizer.load(
+ directory=tokenizer_dir,
+ vocab_size=config.model.vocabulary_size,
+ max_length=config.model.max_length,
+ )
+ model = build_caption_model(config, vocab_size=tokenizer.vocabulary_size)
+ # Build the model once before loading weights — Keras requires a
+ # forward pass before ``load_weights`` knows variable shapes.
+ cls._dummy_pass(model, config)
+ model.load_weights(str(weights_path))
+
+ resolved_strategy: DecodeStrategy = (
+ decode_strategy or config.serve.decode_strategy # type: ignore[assignment]
+ )
+ log.info(
+ "predictor_loaded",
+ weights=str(weights_path),
+ decode_strategy=resolved_strategy,
+ )
+ return cls(
+ model=model,
+ tokenizer=tokenizer,
+ config=config,
+ decode_strategy=resolved_strategy,
+ beam_width=beam_width if beam_width is not None else config.serve.beam_width,
+ length_penalty=(
+ length_penalty if length_penalty is not None else config.serve.length_penalty
+ ),
+ repetition_penalty=(
+ repetition_penalty
+ if repetition_penalty is not None
+ else config.serve.repetition_penalty
+ ),
+ no_repeat_ngram_size=(
+ no_repeat_ngram_size
+ if no_repeat_ngram_size is not None
+ else config.serve.no_repeat_ngram_size
+ ),
+ )
+
+ def warmup(self) -> None:
+ """Run one dummy inference so the first real request is fast."""
+ import tensorflow as tf
+
+ dummy = tf.zeros((299, 299, 3), dtype=tf.float32)
+ _ = self.predict_tensor(dummy)
+ log.info("predictor_warmed_up", decode_strategy=self.decode_strategy)
+
+ def predict_tensor(self, image_tensor, *, decode_strategy: DecodeStrategy | None = None) -> str:
+ """Generate a caption from an already-preprocessed image tensor.
+
+ ``decode_strategy`` overrides the instance default for this call only,
+ so concurrent callers never share a mutable setting. Beam calls use
+ the instance's beam knobs.
+ """
+ strategy = decode_strategy or self.decode_strategy
+ if strategy not in DECODE_STRATEGIES:
+ raise ValueError(f"decode_strategy must be 'greedy' or 'beam', got {strategy!r}")
+ if strategy == "beam":
+ return generate_caption_beam(
+ self.model,
+ self.tokenizer,
+ image_tensor,
+ self.config.model.max_length,
+ beam_width=self.beam_width,
+ length_penalty=self.length_penalty,
+ repetition_penalty=self.repetition_penalty,
+ no_repeat_ngram_size=self.no_repeat_ngram_size,
+ )
+ return generate_caption_greedy(
+ self.model,
+ self.tokenizer,
+ image_tensor,
+ self.config.model.max_length,
+ )
+
+ def predict_path(self, image_path: str | Path) -> str:
+ """Generate a caption from an image on disk."""
+ tensor = load_image_from_path(str(image_path))
+ return self.predict_tensor(tensor)
+
+ # ------------------------------------------------------------- internal --
+
+ @staticmethod
+ def _dummy_pass(model, config: AppConfig) -> None:
+ """Force-build the model so ``load_weights`` knows variable shapes.
+
+ ``ImageCaptioningModel`` has no top-level ``call()`` — it overrides
+ ``train_step``/``test_step`` instead. Keras therefore won't mark the
+ parent ``Model`` as ``built`` even after every sublayer has its
+ variables created, and the HDF5 ``load_weights`` path refuses to
+ proceed against an unbuilt subclassed model. We work around this by
+ (a) calling each sublayer once so its variables are real (shape-
+ matched to the saved checkpoint) and (b) flipping ``model.built``
+ so the loader walks the sublayer scopes inside the file. The actual
+ weights loaded are still those from the checkpoint — this is purely
+ a Keras bookkeeping flag.
+ """
+ import tensorflow as tf
+
+ dummy_img = tf.zeros((1, 299, 299, 3), dtype=tf.float32)
+ dummy_caps = tf.zeros((1, config.model.max_length), dtype=tf.int64)
+ # Calls train_step's underlying ops without doing a gradient step:
+ img_embed = model.cnn_model(dummy_img)
+ encoded = model.encoder(img_embed, training=False)
+ _ = model.decoder(
+ dummy_caps[:, :-1],
+ encoded,
+ training=False,
+ mask=tf.cast(dummy_caps[:, 1:] != 0, tf.int32),
+ )
+ # Augmentation pipeline is tracked as a sublayer of the parent Model
+ # even though inference never invokes it; building it once keeps the
+ # variable tree identical to what `model.fit` produced when Phase 1
+ # weights were saved.
+ if getattr(model, "image_aug", None) is not None:
+ _ = model.image_aug(dummy_img, training=False)
+ # Sublayers are now built; mark the parent built so HDF5 load_weights
+ # accepts the file. Safe because every variable that the checkpoint
+ # references is already materialised on a tracked sublayer.
+ model.built = True
diff --git a/src/captioning/models/__init__.py b/src/captioning/models/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..8e62c6800c9d89ba673bc1e2428b0c8a808f446a
--- /dev/null
+++ b/src/captioning/models/__init__.py
@@ -0,0 +1,29 @@
+"""Models — Keras layers and the top-level captioning model.
+
+Each layer is in its own file so the architecture reads top-to-bottom in a
+file tree, not inside a 200-line cell. Layers compose through ``factory.py``,
+which is the single place that wires hyperparameters from ``AppConfig``.
+
+ encoder_cnn.py InceptionV3 backbone, frozen ImageNet weights
+ transformer_encoder.py 1-layer Transformer encoder over image patches
+ embeddings.py Token + positional embeddings
+ transformer_decoder.py Multi-head causal decoder with cross-attention
+ captioning_model.py ``ImageCaptioningModel`` (custom train/test step)
+ factory.py ``build_caption_model(config, vocab_size)``
+"""
+
+from captioning.models.captioning_model import ImageCaptioningModel
+from captioning.models.embeddings import Embeddings
+from captioning.models.encoder_cnn import build_cnn_encoder
+from captioning.models.factory import build_caption_model
+from captioning.models.transformer_decoder import TransformerDecoderLayer
+from captioning.models.transformer_encoder import TransformerEncoderLayer
+
+__all__ = [
+ "Embeddings",
+ "ImageCaptioningModel",
+ "TransformerDecoderLayer",
+ "TransformerEncoderLayer",
+ "build_caption_model",
+ "build_cnn_encoder",
+]
diff --git a/src/captioning/models/captioning_model.py b/src/captioning/models/captioning_model.py
new file mode 100644
index 0000000000000000000000000000000000000000..0b49287947c3690a9de33f0a16747eed527c6d5a
--- /dev/null
+++ b/src/captioning/models/captioning_model.py
@@ -0,0 +1,134 @@
+"""``ImageCaptioningModel`` — top-level Keras model with custom train/test step.
+
+Mirrors notebook cell 20 verbatim by default. The model owns its own loss &
+accuracy trackers (rather than using compile-time metrics) because the masked
+arithmetic in ``calculate_loss`` / ``calculate_accuracy`` depends on the
+caption padding mask, which Keras's standard metric API can't see.
+
+Two opt-in fixes layered on top of the baseline, both controlled by the
+constructor (defaults preserve the IEEE notebook quirk exactly):
+
+* ``honour_training_flag_in_test_step``
+ The notebook's ``compute_loss_and_acc`` hardcodes ``training=True`` on
+ both the encoder and decoder calls, even when invoked from ``test_step``.
+ That means dropout is active during validation in the IEEE results.
+ Setting this flag to True restores the conventional behaviour — dropout
+ off in test_step — so val_loss reflects deployment behaviour and early
+ stopping fires on a clean signal.
+
+* ``correct_masked_accuracy``
+ The baseline's accuracy tracker is a ``Mean`` of per-batch ratios, which
+ weights small batches the same as large ones. Setting this flag to True
+ feeds the per-batch token count as ``sample_weight`` so the reported
+ metric is a true global token-level masked accuracy.
+
+Both knobs are off by default to keep numeric parity with the notebook; the
+trainer flips them on automatically when the user opts in via
+``train.honour_training_flag_in_test_step``.
+"""
+
+from __future__ import annotations
+
+
+def _build_captioning_model_class():
+ import tensorflow as tf
+
+ class ImageCaptioningModel(tf.keras.Model):
+ """Stitches CNN encoder + Transformer encoder + Transformer decoder."""
+
+ def __init__(
+ self,
+ cnn_model,
+ encoder,
+ decoder,
+ image_aug=None,
+ *,
+ honour_training_flag_in_test_step: bool = False,
+ correct_masked_accuracy: bool = False,
+ ) -> None:
+ super().__init__()
+ self.cnn_model = cnn_model
+ self.encoder = encoder
+ self.decoder = decoder
+ self.image_aug = image_aug
+ self.honour_training_flag_in_test_step = honour_training_flag_in_test_step
+ self.correct_masked_accuracy = correct_masked_accuracy
+ self.loss_tracker = tf.keras.metrics.Mean(name="loss")
+ self.acc_tracker = tf.keras.metrics.Mean(name="accuracy")
+
+ # --- masked metrics (notebook cell 20) -----------------------------
+
+ def calculate_loss(self, y_true, y_pred, mask):
+ loss = self.loss(y_true, y_pred)
+ mask = tf.cast(mask, dtype=loss.dtype)
+ loss *= mask
+ return tf.reduce_sum(loss) / tf.reduce_sum(mask)
+
+ def calculate_accuracy(self, y_true, y_pred, mask):
+ accuracy = tf.equal(y_true, tf.argmax(y_pred, axis=2))
+ accuracy = tf.math.logical_and(mask, accuracy)
+ accuracy = tf.cast(accuracy, dtype=tf.float32)
+ mask = tf.cast(mask, dtype=tf.float32)
+ return tf.reduce_sum(accuracy) / tf.reduce_sum(mask)
+
+ # --- shared loss/acc step (parity quirk: training=True hardcoded) --
+
+ def compute_loss_and_acc(self, img_embed, captions, training=True):
+ # The IEEE notebook hardcoded `training=True` on encoder/decoder
+ # calls even from `test_step`, which means dropout is on during
+ # validation. Honouring the flag (opt-in) restores the standard
+ # behaviour and gives a cleaner val_loss signal.
+ effective_training = bool(training) if self.honour_training_flag_in_test_step else True
+ encoder_output = self.encoder(img_embed, training=effective_training)
+ y_input = captions[:, :-1]
+ y_true = captions[:, 1:]
+ mask = y_true != 0
+ y_pred = self.decoder(y_input, encoder_output, training=effective_training, mask=mask)
+ loss = self.calculate_loss(y_true, y_pred, mask)
+ acc = self.calculate_accuracy(y_true, y_pred, mask)
+ mask_count = tf.reduce_sum(tf.cast(mask, tf.float32))
+ return loss, acc, mask_count
+
+ # --- Keras hooks ---------------------------------------------------
+
+ def train_step(self, batch):
+ imgs, captions = batch
+ if self.image_aug:
+ imgs = self.image_aug(imgs)
+ img_embed = self.cnn_model(imgs)
+
+ with tf.GradientTape() as tape:
+ loss, acc, mask_count = self.compute_loss_and_acc(img_embed, captions)
+
+ train_vars = self.encoder.trainable_variables + self.decoder.trainable_variables
+ grads = tape.gradient(loss, train_vars)
+ self.optimizer.apply_gradients(zip(grads, train_vars, strict=False))
+ self.loss_tracker.update_state(loss)
+ if self.correct_masked_accuracy:
+ # Weight per-batch accuracy by token count so the epoch
+ # average is a true global accuracy, not a mean of ratios.
+ self.acc_tracker.update_state(acc, sample_weight=mask_count)
+ else:
+ self.acc_tracker.update_state(acc)
+
+ return {"loss": self.loss_tracker.result(), "acc": self.acc_tracker.result()}
+
+ def test_step(self, batch):
+ imgs, captions = batch
+ img_embed = self.cnn_model(imgs)
+ loss, acc, mask_count = self.compute_loss_and_acc(img_embed, captions, training=False)
+ self.loss_tracker.update_state(loss)
+ if self.correct_masked_accuracy:
+ self.acc_tracker.update_state(acc, sample_weight=mask_count)
+ else:
+ self.acc_tracker.update_state(acc)
+ return {"loss": self.loss_tracker.result(), "acc": self.acc_tracker.result()}
+
+ @property
+ def metrics(self):
+ return [self.loss_tracker, self.acc_tracker]
+
+ return ImageCaptioningModel
+
+
+ImageCaptioningModel = _build_captioning_model_class()
diff --git a/src/captioning/models/embeddings.py b/src/captioning/models/embeddings.py
new file mode 100644
index 0000000000000000000000000000000000000000..dec6f276e519179840b4b691f504e0b56119f887
--- /dev/null
+++ b/src/captioning/models/embeddings.py
@@ -0,0 +1,56 @@
+"""Token + positional embedding layer.
+
+Mirrors notebook cell 18 verbatim. The decoder learns its own positional
+encoding (rather than using sinusoidal) — that's the published architecture,
+preserved here.
+"""
+
+from __future__ import annotations
+
+
+def _import_tf():
+ """Local import keeps top-level package import lightweight.
+
+ Without this, ``from captioning.models import Embeddings`` would trigger
+ a multi-second TF import even for callers that don't use it.
+ """
+ import tensorflow as tf
+
+ return tf
+
+
+# Defining the class lazily inside a factory keeps TF out of the import path.
+# Callers do ``Embeddings = _build_embeddings_class()`` once at module init.
+def _build_embeddings_class():
+ tf = _import_tf()
+
+ class Embeddings(tf.keras.layers.Layer):
+ """Sum of token and learned positional embeddings.
+
+ Args:
+ vocab_size: Size of the token vocabulary
+ (``CaptionTokenizer.vocabulary_size``).
+ embed_dim: Dimensionality of each embedding vector
+ (``model.embedding_dim``, default 512).
+ max_len: Maximum sequence length (``model.max_length``, default 40).
+ """
+
+ def __init__(self, vocab_size: int, embed_dim: int, max_len: int) -> None:
+ super().__init__()
+ self.token_embeddings = tf.keras.layers.Embedding(vocab_size, embed_dim)
+ self.position_embeddings = tf.keras.layers.Embedding(
+ max_len, embed_dim, input_shape=(None, max_len)
+ )
+
+ def call(self, input_ids):
+ length = tf.shape(input_ids)[-1]
+ position_ids = tf.range(start=0, limit=length, delta=1)
+ position_ids = tf.expand_dims(position_ids, axis=0)
+ token_embeddings = self.token_embeddings(input_ids)
+ position_embeddings = self.position_embeddings(position_ids)
+ return token_embeddings + position_embeddings
+
+ return Embeddings
+
+
+Embeddings = _build_embeddings_class()
diff --git a/src/captioning/models/encoder_cnn.py b/src/captioning/models/encoder_cnn.py
new file mode 100644
index 0000000000000000000000000000000000000000..86731953784bf071c419cb1c43d0e5a8e7b0b50a
--- /dev/null
+++ b/src/captioning/models/encoder_cnn.py
@@ -0,0 +1,36 @@
+"""InceptionV3 image encoder.
+
+Mirrors notebook cell 16. The encoder is the *frozen* visual backbone that
+turns a 299x299 RGB image into a sequence of 2048-dimensional feature vectors
+(one per spatial position in InceptionV3's last conv layer). The Transformer
+encoder/decoder learn on top of these features; the InceptionV3 weights are
+never updated during training.
+
+Why a build function and not a Keras layer? The CNN is constructed from a
+pretrained model whose weights are downloaded the first time. Wrapping
+construction in a function gives callers a single line to invoke, and lets
+us add caching / offline-loading paths later without touching call sites.
+"""
+
+from __future__ import annotations
+
+
+def build_cnn_encoder():
+ """Build the InceptionV3 backbone with the classification head removed.
+
+ Returns:
+ A ``tf.keras.Model`` mapping ``[B, 299, 299, 3]`` images to
+ ``[B, 64, 2048]`` patch features (8x8=64 spatial positions, each a
+ 2048-dim vector — InceptionV3's ``mixed10`` layer).
+ """
+ import tensorflow as tf
+
+ inception = tf.keras.applications.InceptionV3(
+ include_top=False,
+ weights="imagenet",
+ )
+
+ output = inception.output
+ output = tf.keras.layers.Reshape((-1, output.shape[-1]))(output)
+
+ return tf.keras.models.Model(inception.input, output)
diff --git a/src/captioning/models/factory.py b/src/captioning/models/factory.py
new file mode 100644
index 0000000000000000000000000000000000000000..245887ea0998a88ec0bfa6175b191812b881b988
--- /dev/null
+++ b/src/captioning/models/factory.py
@@ -0,0 +1,82 @@
+"""``build_caption_model(config, vocab_size)`` — single place to wire layers.
+
+Mirrors notebook cell 21::
+
+ encoder = TransformerEncoderLayer(EMBEDDING_DIM, 1)
+ decoder = TransformerDecoderLayer(EMBEDDING_DIM, UNITS, 8)
+ cnn_model = CNN_Encoder()
+ caption_model = ImageCaptioningModel(
+ cnn_model=cnn_model,
+ encoder=encoder,
+ decoder=decoder,
+ image_aug=image_augmentation,
+ )
+
+Pulling this into a factory function isolates "how layers are wired" from
+"what hyperparameters they use", so Phase 1b ablations and Phase 5 model
+swaps only touch this file.
+"""
+
+from __future__ import annotations
+
+from captioning.config.schema import AppConfig
+from captioning.models.captioning_model import ImageCaptioningModel
+from captioning.models.encoder_cnn import build_cnn_encoder
+from captioning.models.transformer_decoder import TransformerDecoderLayer
+from captioning.models.transformer_encoder import TransformerEncoderLayer
+from captioning.preprocessing.augmentation import default_image_augmentation
+
+
+def build_caption_model(
+ config: AppConfig,
+ vocab_size: int,
+ *,
+ use_augmentation: bool = True,
+):
+ """Construct a ready-to-compile ``ImageCaptioningModel``.
+
+ Args:
+ config: Validated app config (the ``model`` section is consumed here).
+ vocab_size: Comes from the *fitted* tokenizer
+ (``CaptionTokenizer.vocabulary_size``). The factory does not own
+ tokenizer state — callers fit the tokenizer first, pass the size in.
+ use_augmentation: If True (default), wires
+ ``default_image_augmentation()`` for ``train_step``. Inference and
+ evaluation paths pass False.
+
+ Returns:
+ An uncompiled ``ImageCaptioningModel``. Caller is responsible for
+ ``model.compile(optimizer=..., loss=...)``.
+ """
+ m = config.model
+
+ encoder = TransformerEncoderLayer(m.embedding_dim, m.encoder_num_heads)
+ decoder = TransformerDecoderLayer(
+ embed_dim=m.embedding_dim,
+ units=m.units,
+ num_heads=m.decoder_num_heads,
+ vocab_size=vocab_size,
+ max_len=m.max_length,
+ attention_dropout=m.decoder_attention_dropout,
+ inner_dropout=m.decoder_dropout_inner,
+ outer_dropout=m.decoder_dropout_outer,
+ )
+ cnn = build_cnn_encoder()
+ aug = default_image_augmentation() if use_augmentation else None
+
+ # ``honour_training_flag_in_test_step`` and ``correct_masked_accuracy``
+ # default to False so this factory keeps producing notebook-parity models
+ # unless the user opts in by flipping the corresponding YAML flag.
+ honour_flag = bool(config.train.honour_training_flag_in_test_step)
+ # The masked-accuracy correction is harmless under parity (it's a
+ # better-weighted average of the same per-batch numbers), so we tie it to
+ # the same opt-in flag rather than adding a separate one — keeps the
+ # YAML surface minimal.
+ return ImageCaptioningModel(
+ cnn_model=cnn,
+ encoder=encoder,
+ decoder=decoder,
+ image_aug=aug,
+ honour_training_flag_in_test_step=honour_flag,
+ correct_masked_accuracy=honour_flag,
+ )
diff --git a/src/captioning/models/transformer_decoder.py b/src/captioning/models/transformer_decoder.py
new file mode 100644
index 0000000000000000000000000000000000000000..55d4dfd7701269afcec3ab91b995d1a7349eeba7
--- /dev/null
+++ b/src/captioning/models/transformer_decoder.py
@@ -0,0 +1,130 @@
+"""Multi-head Transformer decoder with causal masking and cross-attention.
+
+Mirrors notebook cell 19. Two changes from the notebook, both behaviour-
+preserving when defaults match:
+
+1. **Globals are now constructor arguments.** The notebook closes over
+ ``tokenizer.vocabulary_size()`` and ``MAX_LENGTH`` from module scope.
+ We pass them in as ``vocab_size`` and ``max_len`` so the decoder can be
+ instantiated in tests, factories, and notebooks without setting up a
+ global tokenizer first.
+2. **Dropout rates and attention head count are configurable** with the
+ notebook values as defaults. This costs nothing today and lets Phase 1b
+ ablations vary them without code changes.
+"""
+
+from __future__ import annotations
+
+from captioning.models.embeddings import Embeddings
+
+
+def _build_transformer_decoder_class():
+ import tensorflow as tf
+
+ class TransformerDecoderLayer(tf.keras.layers.Layer):
+ """Causal self-attention + cross-attention + FFN block.
+
+ Args:
+ embed_dim: Token/positional embedding dimension. Must equal the
+ encoder's ``embed_dim``.
+ units: Hidden dimension of the feed-forward sub-block.
+ num_heads: Multi-head attention heads. Notebook uses 8.
+ vocab_size: Output projection dimension (the model emits softmax
+ probabilities over the vocabulary).
+ max_len: Maximum decode length, used to size positional embeddings.
+ attention_dropout: Dropout applied inside MultiHeadAttention.
+ Notebook uses 0.1.
+ inner_dropout: Dropout after the first dense layer in the FFN.
+ Notebook uses 0.3.
+ outer_dropout: Dropout after the residual + final layernorm.
+ Notebook uses 0.5.
+ """
+
+ def __init__(
+ self,
+ embed_dim: int,
+ units: int,
+ num_heads: int,
+ vocab_size: int,
+ max_len: int,
+ attention_dropout: float = 0.1,
+ inner_dropout: float = 0.3,
+ outer_dropout: float = 0.5,
+ ) -> None:
+ super().__init__()
+ self.embedding = Embeddings(vocab_size, embed_dim, max_len)
+
+ self.attention_1 = tf.keras.layers.MultiHeadAttention(
+ num_heads=num_heads, key_dim=embed_dim, dropout=attention_dropout
+ )
+ self.attention_2 = tf.keras.layers.MultiHeadAttention(
+ num_heads=num_heads, key_dim=embed_dim, dropout=attention_dropout
+ )
+
+ self.layernorm_1 = tf.keras.layers.LayerNormalization()
+ self.layernorm_2 = tf.keras.layers.LayerNormalization()
+ self.layernorm_3 = tf.keras.layers.LayerNormalization()
+
+ self.ffn_layer_1 = tf.keras.layers.Dense(units, activation="relu")
+ self.ffn_layer_2 = tf.keras.layers.Dense(embed_dim)
+
+ self.out = tf.keras.layers.Dense(vocab_size, activation="softmax")
+
+ self.dropout_1 = tf.keras.layers.Dropout(inner_dropout)
+ self.dropout_2 = tf.keras.layers.Dropout(outer_dropout)
+
+ def call(self, input_ids, encoder_output, training, mask=None):
+ embeddings = self.embedding(input_ids)
+
+ combined_mask = None
+ padding_mask = None
+
+ if mask is not None:
+ causal_mask = self.get_causal_attention_mask(embeddings)
+ padding_mask = tf.cast(mask[:, :, tf.newaxis], dtype=tf.int32)
+ combined_mask = tf.cast(mask[:, tf.newaxis, :], dtype=tf.int32)
+ combined_mask = tf.minimum(combined_mask, causal_mask)
+
+ attn_output_1 = self.attention_1(
+ query=embeddings,
+ value=embeddings,
+ key=embeddings,
+ attention_mask=combined_mask,
+ training=training,
+ )
+ out_1 = self.layernorm_1(embeddings + attn_output_1)
+
+ attn_output_2 = self.attention_2(
+ query=out_1,
+ value=encoder_output,
+ key=encoder_output,
+ attention_mask=padding_mask,
+ training=training,
+ )
+ out_2 = self.layernorm_2(out_1 + attn_output_2)
+
+ ffn_out = self.ffn_layer_1(out_2)
+ ffn_out = self.dropout_1(ffn_out, training=training)
+ ffn_out = self.ffn_layer_2(ffn_out)
+
+ ffn_out = self.layernorm_3(ffn_out + out_2)
+ ffn_out = self.dropout_2(ffn_out, training=training)
+ return self.out(ffn_out)
+
+ def get_causal_attention_mask(self, inputs):
+ input_shape = tf.shape(inputs)
+ batch_size, sequence_length = input_shape[0], input_shape[1]
+ i = tf.range(sequence_length)[:, tf.newaxis]
+ j = tf.range(sequence_length)
+ mask = tf.cast(i >= j, dtype="int32")
+ mask = tf.reshape(mask, (1, input_shape[1], input_shape[1]))
+ mult = tf.concat(
+ [tf.expand_dims(batch_size, -1), tf.constant([1, 1], dtype=tf.int32)],
+ axis=0,
+ )
+ return tf.tile(mask, mult)
+
+ return TransformerDecoderLayer
+
+
+TransformerDecoderLayer = _build_transformer_decoder_class()
diff --git a/src/captioning/models/transformer_encoder.py b/src/captioning/models/transformer_encoder.py
new file mode 100644
index 0000000000000000000000000000000000000000..698faa0521ac901b51d34571ffc6f4284f8e7976
--- /dev/null
+++ b/src/captioning/models/transformer_encoder.py
@@ -0,0 +1,45 @@
+"""Single-layer Transformer encoder for image patch features.
+
+Mirrors notebook cell 17 verbatim. The encoder is intentionally minimal
+(1 attention head, 1 layer, 1 dense projection) because the *image* features
+are already produced by InceptionV3 — the Transformer encoder's only job is
+to project them into the decoder's embedding dimension and let the decoder
+attend across patches.
+"""
+
+from __future__ import annotations
+
+
+def _build_transformer_encoder_class():
+ import tensorflow as tf
+
+ class TransformerEncoderLayer(tf.keras.layers.Layer):
+ """Norm → Dense → Self-attention → Norm + Add (post-norm wrapper).
+
+ Args:
+ embed_dim: Dimensionality fed to the dense projection and used as
+ ``key_dim`` for attention. Must equal the decoder's embed_dim.
+ num_heads: Attention heads. Notebook uses 1.
+ """
+
+ def __init__(self, embed_dim: int, num_heads: int) -> None:
+ super().__init__()
+ self.layer_norm_1 = tf.keras.layers.LayerNormalization()
+ self.layer_norm_2 = tf.keras.layers.LayerNormalization()
+ self.attention = tf.keras.layers.MultiHeadAttention(
+ num_heads=num_heads, key_dim=embed_dim
+ )
+ self.dense = tf.keras.layers.Dense(embed_dim, activation="relu")
+
+ def call(self, x, training):
+ x = self.layer_norm_1(x)
+ x = self.dense(x)
+ attn_output = self.attention(
+ query=x, value=x, key=x, attention_mask=None, training=training
+ )
+ return self.layer_norm_2(x + attn_output)
+
+ return TransformerEncoderLayer
+
+
+TransformerEncoderLayer = _build_transformer_encoder_class()
diff --git a/src/captioning/preprocessing/__init__.py b/src/captioning/preprocessing/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..98142f42f2d5d722d0a46ce6b57c2376de6d1354
--- /dev/null
+++ b/src/captioning/preprocessing/__init__.py
@@ -0,0 +1,35 @@
+"""Preprocessing — pure transforms on captions and images.
+
+Functions in this package take inputs and return outputs with no hidden state
+and no disk I/O. That makes them trivially unit-testable and lets us share the
+same logic across the training pipeline (where they're composed into tf.data
+maps) and the inference path (where they're called once per request).
+
+Modules:
+ caption.py ``preprocess_caption(text)`` — lower/strip/wrap with [start]/[end]
+ image.py ``preprocess_image_tensor(img)``, ``load_and_preprocess_image(path)``
+ tokenizer.py ``CaptionTokenizer`` — wraps tf.keras TextVectorization
+ augmentation.py ``default_image_augmentation()`` — Keras Sequential
+"""
+
+from captioning.preprocessing.augmentation import default_image_augmentation
+from captioning.preprocessing.caption import (
+ END_TOKEN,
+ START_TOKEN,
+ preprocess_caption,
+)
+from captioning.preprocessing.image import (
+ load_and_preprocess_image,
+ preprocess_image_tensor,
+)
+from captioning.preprocessing.tokenizer import CaptionTokenizer
+
+__all__ = [
+ "END_TOKEN",
+ "START_TOKEN",
+ "CaptionTokenizer",
+ "default_image_augmentation",
+ "load_and_preprocess_image",
+ "preprocess_caption",
+ "preprocess_image_tensor",
+]
diff --git a/src/captioning/preprocessing/augmentation.py b/src/captioning/preprocessing/augmentation.py
new file mode 100644
index 0000000000000000000000000000000000000000..668dad3cb21bd142a393024bfd817f43163522fa
--- /dev/null
+++ b/src/captioning/preprocessing/augmentation.py
@@ -0,0 +1,35 @@
+"""Image-augmentation pipeline (training only).
+
+Mirrors notebook cell 15. Augmentation is deliberately separate from
+``image.py``: augmentations introduce randomness and only run during training,
+while ``preprocess_image_tensor`` is deterministic and runs in both train and
+serve. Mixing them risks accidentally augmenting at inference time.
+"""
+
+from __future__ import annotations
+
+
+def default_image_augmentation() -> tf.keras.Sequential: # type: ignore[name-defined] # noqa: F821
+ """Build the augmentation chain used during training.
+
+ The model is composed once (notebook cell 21::
+
+ ImageCaptioningModel(..., image_aug=image_augmentation)
+
+ ) and the augmentation block runs only inside ``train_step`` (notebook
+ cell 20). ``test_step`` skips augmentation, which is the correct behaviour
+ we preserve.
+
+ Returns:
+ A ``tf.keras.Sequential`` of ``RandomFlip`` + ``RandomRotation`` +
+ ``RandomContrast`` matching cell 15 exactly.
+ """
+ import tensorflow as tf
+
+ return tf.keras.Sequential(
+ [
+ tf.keras.layers.RandomFlip("horizontal"),
+ tf.keras.layers.RandomRotation(0.2),
+ tf.keras.layers.RandomContrast(0.3),
+ ]
+ )
diff --git a/src/captioning/preprocessing/caption.py b/src/captioning/preprocessing/caption.py
new file mode 100644
index 0000000000000000000000000000000000000000..8a32b920858a68890c01803420e24b7e5008267b
--- /dev/null
+++ b/src/captioning/preprocessing/caption.py
@@ -0,0 +1,58 @@
+"""Caption text preprocessing.
+
+Mirrors the IEEE notebook cell 3::
+
+ def preprocess(text):
+ text = text.lower()
+ text = re.sub(r"[^\\w\\s]", "", text)
+ text = re.sub("\\s+", " ", text)
+ text = text.strip()
+ text = "[start] " + text + " [end]"
+ return text
+
+Why pull this out of the notebook:
+ * It's a *pure function*: same input → same output, no side effects.
+ Easiest possible thing to unit-test, and the lowest-risk module to verify
+ parity on (one ``assert preprocess_caption("Hello, World!") == "[start] hello world [end]"``
+ catches any divergence).
+ * The same logic runs at training time AND at inference time. Centralising
+ it eliminates the most common bug source in ML systems: train/serve skew.
+"""
+
+from __future__ import annotations
+
+import re
+
+START_TOKEN = "[start]"
+END_TOKEN = "[end]"
+
+# Pre-compiled for marginal speed (caption preprocessing is called ~600k+
+# times during dataset prep). The compiled patterns also make intent obvious.
+_PUNCTUATION_RE = re.compile(r"[^\w\s]")
+_WHITESPACE_RE = re.compile(r"\s+")
+
+
+def preprocess_caption(text: str) -> str:
+ """Lowercase, strip punctuation, collapse whitespace, wrap with sentinels.
+
+ Behaviour is byte-for-byte identical to the notebook's ``preprocess()``.
+
+ Args:
+ text: Raw caption string (any case, may contain punctuation).
+
+ Returns:
+ Normalised caption with ``[start]`` and ``[end]`` sentinels, e.g.::
+
+ >>> preprocess_caption("A man, riding a Bike!")
+ '[start] a man riding a bike [end]'
+
+ Note:
+ The notebook applies this function via ``DataFrame.apply``; we don't
+ vectorise here because the regex compilation is the dominant cost and
+ is already amortised over a single call.
+ """
+ text = text.lower()
+ text = _PUNCTUATION_RE.sub("", text)
+ text = _WHITESPACE_RE.sub(" ", text)
+ text = text.strip()
+ return f"{START_TOKEN} {text} {END_TOKEN}"
diff --git a/src/captioning/preprocessing/image.py b/src/captioning/preprocessing/image.py
new file mode 100644
index 0000000000000000000000000000000000000000..87b1abf6f467ea6c5740559b27dbba305a0af9a0
--- /dev/null
+++ b/src/captioning/preprocessing/image.py
@@ -0,0 +1,62 @@
+"""Image preprocessing.
+
+Mirrors notebook cell 13 (training pipeline) and cell 25 (inference path).
+Both paths must produce *byte-identical* tensors — the model only saw 299x299
+images normalised by ``inception_v3.preprocess_input`` during training, so
+serving must do exactly that. Centralising the pipeline here is what
+eliminates train/serve skew.
+
+The two public functions split responsibilities:
+ * ``preprocess_image_tensor`` — operates on an already-decoded image
+ tensor. Used by the tf.data pipeline AND inference (after decode).
+ * ``load_and_preprocess_image`` — reads bytes from disk, decodes, then
+ calls ``preprocess_image_tensor``. Used at inference time.
+
+Both use ``tf.keras.layers.Resizing(299, 299)`` (not ``tf.image.resize``)
+because the notebook uses the layer form. ``Resizing`` defaults to bilinear
+interpolation and rounds to nearest integer dims, which is the exact behaviour
+that produced the IEEE BLEU score.
+"""
+
+from __future__ import annotations
+
+INCEPTION_INPUT_SIZE = 299
+
+
+def preprocess_image_tensor(image: tf.Tensor) -> tf.Tensor: # type: ignore[name-defined] # noqa: F821
+ """Resize to 299x299 and apply ``inception_v3.preprocess_input``.
+
+ Args:
+ image: A 3-D ``tf.Tensor`` of shape ``[H, W, 3]`` and dtype ``uint8``
+ or ``float32``. The Resizing layer accepts both.
+
+ Returns:
+ ``tf.Tensor`` of shape ``[299, 299, 3]``, dtype ``float32``, with the
+ InceptionV3 normalisation applied (pixel values in ``[-1, 1]``).
+ """
+ import tensorflow as tf
+
+ image = tf.keras.layers.Resizing(INCEPTION_INPUT_SIZE, INCEPTION_INPUT_SIZE)(image)
+ return tf.keras.applications.inception_v3.preprocess_input(image)
+
+
+def load_and_preprocess_image(image_path: str) -> tf.Tensor: # type: ignore[name-defined] # noqa: F821
+ """Read a JPEG from disk and run it through ``preprocess_image_tensor``.
+
+ Args:
+ image_path: Path to a JPEG file. Strings, ``pathlib.Path``, and
+ ``tf.string`` tensors all work — the latter matters because
+ ``tf.data`` pipelines pass paths as tensors.
+
+ Returns:
+ A 3-D ``tf.Tensor`` ready to feed into the CNN encoder.
+
+ Raises:
+ tf.errors.NotFoundError: If the file does not exist.
+ tf.errors.InvalidArgumentError: If the file is not a valid JPEG/PNG.
+ """
+ import tensorflow as tf
+
+ raw = tf.io.read_file(image_path)
+ image = tf.io.decode_jpeg(raw, channels=3)
+ return preprocess_image_tensor(image)
diff --git a/src/captioning/preprocessing/tokenizer.py b/src/captioning/preprocessing/tokenizer.py
new file mode 100644
index 0000000000000000000000000000000000000000..89932dbf3b476b527fd66307bddc60caba540a70
--- /dev/null
+++ b/src/captioning/preprocessing/tokenizer.py
@@ -0,0 +1,313 @@
+"""``CaptionTokenizer`` — typed wrapper around ``tf.keras.layers.TextVectorization``.
+
+Why a wrapper instead of using the Keras layer directly?
+
+1. **Stable interface for the model.** The model code calls
+ ``tokenizer.encode(captions)`` and ``tokenizer.decode_id(idx)``. The fact
+ that those happen to delegate to a Keras layer is an implementation
+ detail. In Phase 5 we may swap the implementation for HuggingFace
+ ``tokenizers`` without rewriting the encoder, decoder, or inference loop.
+2. **Persistence.** The notebook saves the *vocabulary list* with pickle, but
+ loading requires re-instantiating a layer and calling ``set_vocabulary``.
+ That ceremony belongs inside the wrapper, not at every call site.
+3. **A JSON sidecar.** Pickle is fast but opaque, and loading one can run
+ code. We additionally write a ``vocab.json`` file (a JSON array, one token
+ per line, UTF-8) so humans and other tools can inspect the vocabulary.
+ ``load`` reads and validates that file first. It reads a pickle only when
+ there is no JSON file, and refuses any pickle that names a global other
+ than the two NumPy uses to rebuild string scalars.
+
+The wrapper preserves the notebook's behaviour exactly: ``standardize=None``,
+``output_sequence_length`` defaults to ``max_length``, and ``encode`` accepts
+either a single string or a list of strings (matching the layer's call form
+used in cells 7 and 25).
+"""
+
+from __future__ import annotations
+
+import json
+import pickle
+from collections.abc import Iterable
+from pathlib import Path
+from typing import Any
+
+VOCAB_PICKLE_FILENAME = "vocab.pkl"
+VOCAB_JSON_FILENAME = "vocab.json"
+
+# TextVectorization's padding and OOV tokens. ``get_vocabulary()`` returns them
+# at ids 0 and 1, so every saved vocabulary starts with them.
+_RESERVED_TOKENS = ("", "[UNK]")
+
+# The only globals a vocabulary pickle may name. The notebook pickles
+# ``get_vocabulary()``, whose entries can be ``numpy.str_``, and unpickling
+# those needs NumPy's dtype and scalar reconstructor. Neither calls arbitrary
+# code: they only build a dtype and a scalar from the pickled values.
+_ALLOWED_PICKLE_GLOBALS = frozenset({("numpy", "dtype"), ("numpy.core.multiarray", "scalar")})
+
+
+class _VocabularyUnpickler(pickle.Unpickler):
+ """Unpickler that refuses every global outside ``_ALLOWED_PICKLE_GLOBALS``."""
+
+ def find_class(self, module: str, name: str) -> Any:
+ if (module, name) not in _ALLOWED_PICKLE_GLOBALS:
+ raise pickle.UnpicklingError(f"refused global {module}.{name}")
+ return super().find_class(module, name)
+
+
+def read_vocabulary(directory: str | Path, vocab_size: int) -> list[str]:
+ """Read and validate a saved vocabulary list, without importing TensorFlow.
+
+ ``vocab.json`` wins when both files exist. ``vocab.pkl`` is read only when
+ there is no JSON file, through ``_VocabularyUnpickler``.
+
+ Args:
+ directory: Directory containing ``vocab.json`` or ``vocab.pkl``.
+ vocab_size: Maximum vocabulary size the model was built with.
+
+ Returns:
+ The tokens in id order, as plain ``str``.
+
+ Raises:
+ FileNotFoundError: Neither file exists.
+ ValueError: The file can't be parsed, or its list isn't a vocabulary
+ this tokenizer could have saved.
+ """
+ directory = Path(directory)
+ js = directory / VOCAB_JSON_FILENAME
+ pkl = directory / VOCAB_PICKLE_FILENAME
+ if js.is_file():
+ source = js
+ try:
+ with js.open(encoding="utf-8") as f:
+ vocab = json.load(f)
+ except ValueError as exc: # JSONDecodeError, UnicodeDecodeError
+ raise ValueError(f"Could not parse tokenizer vocabulary {js}: {exc}") from exc
+ elif pkl.is_file():
+ source = pkl
+ try:
+ with pkl.open("rb") as f:
+ vocab = _VocabularyUnpickler(f).load()
+ except Exception as exc: # malformed pickles raise many exception types
+ raise ValueError(f"Could not read tokenizer vocabulary {pkl}: {exc}") from exc
+ else:
+ raise FileNotFoundError(
+ f"No tokenizer vocabulary found in {directory!s}. "
+ f"Expected '{VOCAB_JSON_FILENAME}' (preferred) or "
+ f"'{VOCAB_PICKLE_FILENAME}'. Train the model with "
+ "`python -m scripts.train --config configs/base.yaml` to "
+ "produce the artefacts, or point BACKEND_TOKENIZER_DIR at a "
+ "directory that contains them."
+ )
+ return _validate_vocabulary(vocab, source, vocab_size)
+
+
+def _validate_vocabulary(vocab: object, source: Path, vocab_size: int) -> list[str]:
+ """Return ``vocab`` as plain strings, or raise ``ValueError`` naming ``source``."""
+ if not isinstance(vocab, list):
+ raise ValueError(
+ f"Tokenizer vocabulary {source} must be a list of strings, "
+ f"got {type(vocab).__name__}."
+ )
+ for index, token in enumerate(vocab):
+ if not isinstance(token, str):
+ raise ValueError(
+ f"Tokenizer vocabulary {source} has a non-string entry at id {index}: "
+ f"{type(token).__name__}."
+ )
+ tokens = [str(token) for token in vocab] # numpy.str_ -> str
+ if tuple(tokens[:2]) != _RESERVED_TOKENS:
+ raise ValueError(
+ f"Tokenizer vocabulary {source} must start with the padding and OOV tokens "
+ f"{list(_RESERVED_TOKENS)!r}, got {tokens[:2]!r}."
+ )
+ seen: set[str] = set()
+ for token in tokens:
+ if token in seen:
+ raise ValueError(f"Tokenizer vocabulary {source} repeats the token {token!r}.")
+ seen.add(token)
+ if len(tokens) > vocab_size:
+ raise ValueError(
+ f"Tokenizer vocabulary {source} has {len(tokens)} entries, "
+ f"more than vocab_size={vocab_size}."
+ )
+ return tokens
+
+
+class CaptionTokenizer:
+ """Wrapper that owns a fitted ``TextVectorization`` layer + lookup tables."""
+
+ def __init__(self, vocab_size: int, max_length: int) -> None:
+ """Construct an unfit tokenizer.
+
+ Args:
+ vocab_size: Maximum vocabulary size (notebook: ``VOCABULARY_SIZE``).
+ max_length: Pad/truncate every caption to this many tokens
+ (notebook: ``MAX_LENGTH``).
+ """
+ self.vocab_size = vocab_size
+ self.max_length = max_length
+ self._layer = None
+ self._idx2word = None
+ self._word2idx = None
+
+ # ----------------------------------------------------------------- fit ----
+
+ def fit(self, captions: Iterable[str]) -> None:
+ """Adapt the underlying TextVectorization layer to the given captions.
+
+ Args:
+ captions: An iterable of *already preprocessed* captions
+ (i.e. lower-cased, punctuation-stripped, wrapped in
+ ``[start] ... [end]``). Mirrors notebook cell 7 which calls
+ ``tokenizer.adapt(captions['caption'])`` *after* cell 4 has
+ applied ``preprocess`` to every row.
+ """
+ import tensorflow as tf
+
+ layer = tf.keras.layers.TextVectorization(
+ max_tokens=self.vocab_size,
+ standardize=None,
+ output_sequence_length=self.max_length,
+ )
+ layer.adapt(list(captions))
+ self._layer = layer
+ self._build_lookups()
+
+ # ----------------------------------------------------------- properties ---
+
+ @property
+ def vocabulary(self) -> list[str]:
+ """Return the fitted vocabulary list (same order as TextVectorization)."""
+ layer = self._require_fit()
+ return list(layer.get_vocabulary())
+
+ @property
+ def vocabulary_size(self) -> int:
+ """Number of tokens in the fitted vocabulary."""
+ return int(self._require_fit().vocabulary_size())
+
+ @property
+ def layer(self):
+ """Direct access to the inner Keras layer.
+
+ Exposed because the model's ``Embeddings`` layer (notebook cell 19)
+ needs ``tokenizer.vocabulary_size()`` at construction time. Phase 1b
+ replaces this with a constructor argument and removes the property.
+ """
+ return self._require_fit()
+
+ # -------------------------------------------------------- encode/decode ---
+
+ def encode(self, text):
+ """Encode ``text`` (str or list[str]) to integer-id tensor.
+
+ Mirrors ``tokenizer(text)`` in notebook cells 7 and 25. Single string
+ returns a 1-D tensor of shape ``[max_length]``; list returns 2-D.
+ """
+ return self._require_fit()(text)
+
+ def decode_id(self, idx) -> str:
+ """Inverse-lookup a single integer id to its string token.
+
+ Mirrors notebook cell 25's
+ ``idx2word(pred_idx).numpy().decode('utf-8')``.
+ """
+ self._require_fit()
+ # By invariant, _idx2word is set together with _layer in fit/load.
+ assert self._idx2word is not None
+ word = self._idx2word(idx)
+ return word.numpy().decode("utf-8")
+
+ def word_to_id(self, word: str) -> int:
+ """Look up a single word's integer id, returning 1 (the OOV id) if absent.
+
+ Used by beam search to seed beams with the ``[start]`` token without
+ going through ``TextVectorization``'s padded-string path.
+ """
+ self._require_fit()
+ assert self._word2idx is not None
+ return int(self._word2idx(word).numpy())
+
+ # ---------------------------------------------------------- persistence ---
+
+ def save(self, directory: str | Path) -> None:
+ """Save the vocabulary to ``directory/vocab.pkl`` and ``vocab.json``.
+
+ The pickle matches notebook cell 9 exactly so old artefacts remain
+ loadable. The JSON sidecar is human-inspectable.
+ """
+ self._require_fit()
+ directory = Path(directory)
+ directory.mkdir(parents=True, exist_ok=True)
+ vocab = self.vocabulary
+ with (directory / VOCAB_PICKLE_FILENAME).open("wb") as f:
+ pickle.dump(vocab, f)
+ with (directory / VOCAB_JSON_FILENAME).open("w", encoding="utf-8") as f:
+ json.dump(vocab, f, ensure_ascii=False, indent=2)
+
+ @classmethod
+ def load(
+ cls,
+ directory: str | Path,
+ vocab_size: int,
+ max_length: int,
+ ) -> CaptionTokenizer:
+ """Load a previously saved vocabulary into a new tokenizer.
+
+ Args:
+ directory: Directory containing ``vocab.json`` (preferred) or
+ ``vocab.pkl``.
+ vocab_size: Maximum vocabulary size — must match the saved vocab.
+ max_length: Pad/truncate length — must match training-time value.
+
+ Returns:
+ A fitted ``CaptionTokenizer`` ready to ``encode`` and ``decode_id``.
+
+ Raises:
+ FileNotFoundError: Neither vocabulary file exists.
+ ValueError: The vocabulary is malformed (see ``read_vocabulary``).
+ """
+ vocab = read_vocabulary(directory, vocab_size)
+
+ import tensorflow as tf
+
+ tok = cls(vocab_size=vocab_size, max_length=max_length)
+ layer = tf.keras.layers.TextVectorization(
+ max_tokens=vocab_size,
+ standardize=None,
+ output_sequence_length=max_length,
+ )
+ layer.set_vocabulary(vocab)
+ tok._layer = layer
+ tok._build_lookups()
+ return tok
+
+ # -------------------------------------------------------------- internal --
+
+ def _build_lookups(self) -> None:
+ """Construct ``StringLookup`` (idx → word) for inference decoding.
+
+ Called only from ``fit()`` and ``load()``, *after* ``self._layer`` has
+ been assigned, so the assertion below is a defensive no-op for mypy.
+ """
+ import tensorflow as tf
+
+ assert self._layer is not None
+ vocab = self._layer.get_vocabulary()
+ self._word2idx = tf.keras.layers.StringLookup(mask_token="", vocabulary=vocab)
+ self._idx2word = tf.keras.layers.StringLookup(mask_token="", vocabulary=vocab, invert=True)
+
+ def _require_fit(self):
+ """Validate that the tokenizer has been fitted; return the inner layer.
+
+ Returning the layer (rather than only raising on the unfit state)
+ gives callers a non-``None``-typed local for the rest of their body —
+ which is what mypy needs to prove ``layer.get_vocabulary()`` etc.
+ are valid calls. Costs one attribute lookup at runtime.
+ """
+ if self._layer is None:
+ raise RuntimeError(
+ "CaptionTokenizer not fitted. Call `.fit(captions)` or "
+ "`.load(directory, ...)` first."
+ )
+ return self._layer
diff --git a/src/captioning/py.typed b/src/captioning/py.typed
new file mode 100644
index 0000000000000000000000000000000000000000..e69de29bb2d1d6434b8b29ae775ad8c2e48c5391
diff --git a/src/captioning/training/__init__.py b/src/captioning/training/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..10116a8f8227b6b51274daade0fda34569f80d1b
--- /dev/null
+++ b/src/captioning/training/__init__.py
@@ -0,0 +1,31 @@
+"""Training — losses, schedules, callbacks, and the trainer.
+
+The notebook computes loss + masked accuracy inside the model's ``train_step``;
+we keep that structure for parity but expose the loss function and callbacks
+as standalone modules so they can be unit-tested and reused.
+
+ losses.py ``masked_sparse_categorical_crossentropy`` (baseline) +
+ ``label_smoothed_crossentropy`` + ``build_loss``
+ schedules.py ``WarmupCosineDecay`` + ``build_learning_rate``
+ callbacks.py ``default_callbacks(config)`` — early stopping + checkpoint
+ trainer.py ``Trainer.fit()`` — wraps compile + fit + history serialization
+"""
+
+from captioning.training.callbacks import default_callbacks
+from captioning.training.losses import (
+ build_loss,
+ label_smoothed_crossentropy,
+ masked_sparse_categorical_crossentropy,
+)
+from captioning.training.schedules import WarmupCosineDecay, build_learning_rate
+from captioning.training.trainer import Trainer
+
+__all__ = [
+ "Trainer",
+ "WarmupCosineDecay",
+ "build_learning_rate",
+ "build_loss",
+ "default_callbacks",
+ "label_smoothed_crossentropy",
+ "masked_sparse_categorical_crossentropy",
+]
diff --git a/src/captioning/training/callbacks.py b/src/captioning/training/callbacks.py
new file mode 100644
index 0000000000000000000000000000000000000000..417ff69edff1bc57d0b63a82842af25ce4236d72
--- /dev/null
+++ b/src/captioning/training/callbacks.py
@@ -0,0 +1,55 @@
+"""Default training callbacks.
+
+Mirrors notebook cell 22 (``EarlyStopping(patience=3, restore_best_weights=True)``)
+and adds Phase-2 hooks (``ModelCheckpoint``, ``CSVLogger``) that the trainer
+will use. Each callback is created by a tiny factory so callers don't have to
+import TF for the names.
+"""
+
+from __future__ import annotations
+
+from pathlib import Path
+
+from captioning.config.schema import AppConfig
+
+
+def default_callbacks(
+ config: AppConfig,
+ *,
+ output_dir: str | Path | None = None,
+):
+ """Return the list of callbacks ``Trainer.fit`` will pass to ``model.fit``.
+
+ Args:
+ config: App config (uses ``train.early_stopping_patience``).
+ output_dir: If provided, ``ModelCheckpoint`` writes ``best.h5`` and
+ ``CSVLogger`` writes ``training_log.csv`` here. Notebook does
+ neither — these are Phase-1b improvements layered on top of the
+ parity baseline. They run *before* parity is exercised because
+ adding a callback does not change loss values, only emits files.
+
+ Returns:
+ A list of ``tf.keras.callbacks.Callback`` instances.
+ """
+ import tensorflow as tf
+
+ callbacks = [
+ tf.keras.callbacks.EarlyStopping(
+ patience=config.train.early_stopping_patience,
+ restore_best_weights=True,
+ ),
+ ]
+
+ if output_dir is not None:
+ out = Path(output_dir)
+ out.mkdir(parents=True, exist_ok=True)
+ callbacks += [
+ tf.keras.callbacks.ModelCheckpoint(
+ filepath=str(out / "best.h5"),
+ save_weights_only=True,
+ save_best_only=True,
+ monitor="val_loss",
+ ),
+ tf.keras.callbacks.CSVLogger(str(out / "training_log.csv")),
+ ]
+ return callbacks
diff --git a/src/captioning/training/losses.py b/src/captioning/training/losses.py
new file mode 100644
index 0000000000000000000000000000000000000000..b62f3d7706f57f8df79a931cef1447a2bd2e450c
--- /dev/null
+++ b/src/captioning/training/losses.py
@@ -0,0 +1,83 @@
+"""Training losses.
+
+The notebook (cell 22) compiles the model with::
+
+ cross_entropy = tf.keras.losses.SparseCategoricalCrossentropy(from_logits=False, reduction="none")
+
+Why ``reduction="none"``: the model's ``calculate_loss`` (cell 20) does the
+reduction itself, multiplying by the padding mask before averaging. A built-in
+reduction would average over the padded tokens too, biasing the loss.
+
+For the stabilisation phase we also support label-smoothed cross-entropy.
+Label smoothing replaces the one-hot target ``y_true`` with a mixture of the
+true label and a uniform distribution over the vocabulary:
+
+ target = (1 - eps) * one_hot(y) + eps / vocab_size
+
+The decoder's output is already softmaxed (`Dense(..., activation='softmax')`),
+so the loss reduces to ``-sum(target * log(p), axis=-1)``. Smoothing
+discourages the decoder from collapsing to a few high-probability tokens —
+the most common failure mode of cross-entropy-trained captioners and a
+likely root cause of the generic captions we're trying to fix.
+"""
+
+from __future__ import annotations
+
+
+def masked_sparse_categorical_crossentropy():
+ """Return the loss function the model is compiled with.
+
+ Same as notebook cell 22: ``from_logits=False, reduction="none"``. The
+ decoder applies a softmax already (``Dense(..., activation="softmax")``)
+ so logits=False is correct.
+ """
+ import tensorflow as tf
+
+ return tf.keras.losses.SparseCategoricalCrossentropy(from_logits=False, reduction="none")
+
+
+def label_smoothed_crossentropy(label_smoothing: float, vocab_size: int):
+ """Per-token cross-entropy with uniform label smoothing.
+
+ Returned callable has the same signature as the sparse loss above
+ (``loss(y_true, y_pred) -> [B, T]``) so the model's masking machinery in
+ ``ImageCaptioningModel.calculate_loss`` works unchanged.
+
+ Args:
+ label_smoothing: Smoothing strength in ``[0, 1)``. ``0.0`` reduces to
+ the sparse-categorical baseline.
+ vocab_size: Size of the output distribution (matches the decoder's
+ final ``Dense`` units). Used to compute the uniform component.
+ """
+ import tensorflow as tf
+
+ if label_smoothing == 0.0:
+ return masked_sparse_categorical_crossentropy()
+
+ eps = float(label_smoothing)
+ log_eps = tf.constant(1e-12, dtype=tf.float32)
+ vocab = int(vocab_size)
+ uniform = eps / float(vocab)
+
+ def loss_fn(y_true, y_pred):
+ # y_true: [B, T] int ids; y_pred: [B, T, V] softmax probabilities.
+ y_pred = tf.cast(y_pred, tf.float32)
+ one_hot = tf.one_hot(tf.cast(y_true, tf.int32), depth=vocab, dtype=tf.float32)
+ target = one_hot * (1.0 - eps) + uniform
+ # Standard cross-entropy on softmax probs. Add log_eps to avoid log(0)
+ # on padding columns where the model would otherwise emit 0.
+ return -tf.reduce_sum(target * tf.math.log(y_pred + log_eps), axis=-1)
+
+ return loss_fn
+
+
+def build_loss(label_smoothing: float, vocab_size: int):
+ """Pick the right loss based on ``label_smoothing``.
+
+ Convenience wrapper so the trainer never has to branch on the smoothing
+ value itself — it always calls ``build_loss(...)`` and the right
+ implementation comes back.
+ """
+ if label_smoothing == 0.0:
+ return masked_sparse_categorical_crossentropy()
+ return label_smoothed_crossentropy(label_smoothing, vocab_size)
diff --git a/src/captioning/training/schedules.py b/src/captioning/training/schedules.py
new file mode 100644
index 0000000000000000000000000000000000000000..61c56169e36c06cf79c7097a5ce56339e69aaf26
--- /dev/null
+++ b/src/captioning/training/schedules.py
@@ -0,0 +1,107 @@
+"""Learning-rate schedules.
+
+The baseline pipeline uses a constant Adam LR (matching the IEEE notebook),
+which is fine for short fine-tuning runs but tends to leave Transformer
+captioners in a mediocre local minimum: the LR is too aggressive at start
+(decoder weights are still random) and too high near convergence (the model
+oscillates around a flat basin instead of settling).
+
+The fix the literature converged on is linear warmup followed by cosine
+decay (the GPT/BERT/ViT recipe):
+
+ lr(step) = peak_lr * step / warmup_steps if step < warmup
+ lr(step) = min_lr + (peak_lr - min_lr) * 0.5 *
+ (1 + cos(pi * (step - warmup) / decay_steps)) otherwise
+
+We implement it as a ``LearningRateSchedule`` so the optimizer can call it
+per-step automatically, without us having to track step counts manually.
+"""
+
+from __future__ import annotations
+
+
+def _build_warmup_cosine_class():
+ """Lazy-build the schedule class to keep TF off the package import path."""
+ import tensorflow as tf
+
+ class WarmupCosineDecay(tf.keras.optimizers.schedules.LearningRateSchedule):
+ """Linear warmup followed by cosine decay to ``min_learning_rate``.
+
+ Args:
+ peak_learning_rate: Maximum LR reached at the end of warmup.
+ warmup_steps: Number of steps to linearly ramp from 0 to peak.
+ ``0`` disables warmup (starts directly at ``peak``).
+ decay_steps: Number of steps over which to cosine-decay from
+ ``peak`` to ``min_learning_rate`` after warmup.
+ min_learning_rate: Floor reached at the end of decay (and held
+ thereafter).
+ """
+
+ def __init__(
+ self,
+ peak_learning_rate: float,
+ warmup_steps: int,
+ decay_steps: int,
+ min_learning_rate: float = 0.0,
+ ) -> None:
+ super().__init__()
+ self.peak_learning_rate = float(peak_learning_rate)
+ self.warmup_steps = int(warmup_steps)
+ self.decay_steps = max(int(decay_steps), 1)
+ self.min_learning_rate = float(min_learning_rate)
+
+ def __call__(self, step):
+ step = tf.cast(step, tf.float32)
+ peak = tf.constant(self.peak_learning_rate, dtype=tf.float32)
+ floor = tf.constant(self.min_learning_rate, dtype=tf.float32)
+ warmup = tf.constant(float(self.warmup_steps), dtype=tf.float32)
+ decay = tf.constant(float(self.decay_steps), dtype=tf.float32)
+
+ # During warmup: linear ramp 0 -> peak.
+ warmup_lr = peak * tf.math.divide_no_nan(step, warmup)
+
+ # After warmup: cosine decay peak -> floor over decay_steps.
+ progress = tf.minimum(1.0, tf.math.divide_no_nan(step - warmup, decay))
+ cosine = 0.5 * (1.0 + tf.cos(tf.constant(3.141592653589793) * progress))
+ decay_lr = floor + (peak - floor) * cosine
+
+ return tf.where(step < warmup, warmup_lr, decay_lr)
+
+ def get_config(self) -> dict[str, float | int]:
+ return {
+ "peak_learning_rate": self.peak_learning_rate,
+ "warmup_steps": self.warmup_steps,
+ "decay_steps": self.decay_steps,
+ "min_learning_rate": self.min_learning_rate,
+ }
+
+ return WarmupCosineDecay
+
+
+WarmupCosineDecay = _build_warmup_cosine_class()
+
+
+def build_learning_rate(
+ *,
+ schedule: str,
+ peak_learning_rate: float,
+ warmup_steps: int,
+ decay_steps: int,
+ min_learning_rate: float,
+):
+ """Return either a float (constant LR) or a :class:`WarmupCosineDecay`.
+
+ The optimizer treats a float as a fixed LR and a ``LearningRateSchedule``
+ as a per-step callable — we hide that asymmetry behind this factory so
+ the trainer only ever passes ``learning_rate=build_learning_rate(...)``.
+ """
+ if schedule == "constant":
+ return peak_learning_rate
+ if schedule == "cosine":
+ return WarmupCosineDecay(
+ peak_learning_rate=peak_learning_rate,
+ warmup_steps=warmup_steps,
+ decay_steps=decay_steps,
+ min_learning_rate=min_learning_rate,
+ )
+ raise ValueError(f"unsupported lr_schedule: {schedule!r}")
diff --git a/src/captioning/training/trainer.py b/src/captioning/training/trainer.py
new file mode 100644
index 0000000000000000000000000000000000000000..6b2bc45d845c103b3b0dd64eabce244b11ce84d7
--- /dev/null
+++ b/src/captioning/training/trainer.py
@@ -0,0 +1,141 @@
+"""``Trainer`` — orchestration around ``model.compile + model.fit``.
+
+Wraps notebook cells 22 and 23 in a class so:
+ * Tests can construct a Trainer with a tiny dataset and assert
+ ``trainer.fit`` returns a sensible history dict.
+ * Phase 4 can replace the trainer with a CLI-driven main loop without
+ changing the notebook-equivalent behaviour.
+
+The trainer reads the optional training-stability fields off ``TrainConfig``
+(``label_smoothing``, ``lr_schedule``, ``warmup_steps``, ...). With defaults
+in place every existing config produces a byte-identical compile call to the
+notebook; flipping one YAML flag opts a run into the modern recipe without
+touching code.
+"""
+
+from __future__ import annotations
+
+import json
+from pathlib import Path
+
+from captioning.config.schema import AppConfig
+from captioning.training.callbacks import default_callbacks
+from captioning.training.losses import build_loss
+from captioning.training.schedules import build_learning_rate
+from captioning.utils.logging import get_logger
+
+log = get_logger(__name__)
+
+
+def _infer_steps_per_epoch(dataset) -> int | None:
+ """Best-effort cardinality probe for a ``tf.data.Dataset``.
+
+ Returns ``None`` when the dataset's cardinality is unknown or infinite.
+ Used only to derive ``cosine_decay_steps`` when the user didn't pin it
+ explicitly.
+ """
+ try:
+ import tensorflow as tf
+
+ card = int(tf.data.experimental.cardinality(dataset).numpy())
+ except Exception: # — cardinality probing is best-effort
+ return None
+ if card in (-1, -2): # UNKNOWN, INFINITE
+ return None
+ return card
+
+
+class Trainer:
+ """Thin orchestration layer around an ``ImageCaptioningModel``."""
+
+ def __init__(self, model, config: AppConfig) -> None:
+ """Args:
+ model: Result of ``build_caption_model(config, vocab_size)``.
+ config: Validated ``AppConfig``.
+ """
+ self.model = model
+ self.config = config
+ self._compiled = False
+
+ def compile(self, *, steps_per_epoch: int | None = None) -> None:
+ """Build optimizer + loss from config and call ``model.compile``.
+
+ Args:
+ steps_per_epoch: Used to derive ``cosine_decay_steps`` when the
+ config doesn't pin it explicitly. Passing ``None`` falls back
+ to the config value (or 1 if neither is set — degenerates to
+ immediate floor LR, but still a well-defined schedule).
+ """
+ import tensorflow as tf
+
+ train = self.config.train
+ # Vocab size lives on the decoder's final Dense layer; pulling it here
+ # avoids threading the tokenizer through the trainer just for loss.
+ vocab_size = int(self.model.decoder.out.units)
+ loss = build_loss(train.label_smoothing, vocab_size)
+
+ cosine_steps = train.cosine_decay_steps or (
+ (steps_per_epoch or 1) * max(train.epochs - 0, 1)
+ )
+ learning_rate = build_learning_rate(
+ schedule=train.lr_schedule,
+ peak_learning_rate=train.learning_rate,
+ warmup_steps=train.warmup_steps,
+ decay_steps=cosine_steps,
+ min_learning_rate=train.min_learning_rate,
+ )
+
+ self.model.compile(
+ optimizer=tf.keras.optimizers.Adam(learning_rate=learning_rate),
+ loss=loss,
+ )
+ self._compiled = True
+ log.info(
+ "model_compiled",
+ lr_schedule=train.lr_schedule,
+ peak_learning_rate=train.learning_rate,
+ warmup_steps=train.warmup_steps,
+ cosine_decay_steps=cosine_steps,
+ label_smoothing=train.label_smoothing,
+ )
+
+ def fit(
+ self,
+ train_dataset,
+ val_dataset,
+ *,
+ output_dir: str | Path | None = None,
+ ) -> dict[str, list[float]]:
+ """Run ``model.fit`` and return a history dict.
+
+ Args:
+ train_dataset: ``tf.data.Dataset`` from
+ ``data.pipeline.build_train_pipeline``.
+ val_dataset: ``tf.data.Dataset`` from
+ ``data.pipeline.build_val_pipeline``.
+ output_dir: If provided, callbacks write ``best.h5`` and
+ ``training_log.csv`` here, and ``history.json`` is dumped at
+ the end.
+
+ Returns:
+ ``history.history`` as a ``dict[str, list[float]]``.
+ """
+ if not self._compiled:
+ self.compile(steps_per_epoch=_infer_steps_per_epoch(train_dataset))
+
+ callbacks = default_callbacks(self.config, output_dir=output_dir)
+ log.info("fit_start", epochs=self.config.train.epochs)
+ history = self.model.fit(
+ train_dataset,
+ epochs=self.config.train.epochs,
+ validation_data=val_dataset,
+ callbacks=callbacks,
+ )
+ log.info("fit_end", final_loss=history.history.get("loss", [None])[-1])
+
+ if output_dir is not None:
+ history_path = Path(output_dir) / "history.json"
+ with history_path.open("w", encoding="utf-8") as f:
+ json.dump(history.history, f, indent=2)
+
+ return dict(history.history)
diff --git a/src/captioning/utils/__init__.py b/src/captioning/utils/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..5f3168039250850e6f477e78f355f17b87885eb7
--- /dev/null
+++ b/src/captioning/utils/__init__.py
@@ -0,0 +1,20 @@
+"""Utils — cross-cutting helpers used by every other sub-package.
+
+Kept deliberately small. If a "util" grows past a single function, that's a
+signal it belongs in its own package, not here.
+
+ logging.py structlog setup (JSON in prod, pretty in dev)
+ seed.py ``set_global_seed`` for reproducibility
+ hashing.py ``sha256_file`` for the paper-notebook freeze check
+"""
+
+from captioning.utils.hashing import sha256_file
+from captioning.utils.logging import configure_logging, get_logger
+from captioning.utils.seed import set_global_seed
+
+__all__ = [
+ "configure_logging",
+ "get_logger",
+ "set_global_seed",
+ "sha256_file",
+]
diff --git a/src/captioning/utils/hashing.py b/src/captioning/utils/hashing.py
new file mode 100644
index 0000000000000000000000000000000000000000..f6bad6cd5c5b55eddf62d31e1a8343bfcb6159f2
--- /dev/null
+++ b/src/captioning/utils/hashing.py
@@ -0,0 +1,22 @@
+"""File-hashing helper used by the paper-notebook freeze CI check."""
+
+from __future__ import annotations
+
+import hashlib
+from pathlib import Path
+
+_CHUNK = 64 * 1024
+
+
+def sha256_file(path: str | Path) -> str:
+ """Return the hex-digest SHA-256 of a file, streaming 64KB chunks.
+
+ Streaming (rather than ``open(...).read()``) keeps memory bounded for
+ notebooks with embedded image outputs that can hit hundreds of MB.
+ """
+ h = hashlib.sha256()
+ path = Path(path)
+ with path.open("rb") as f:
+ while chunk := f.read(_CHUNK):
+ h.update(chunk)
+ return h.hexdigest()
diff --git a/src/captioning/utils/logging.py b/src/captioning/utils/logging.py
new file mode 100644
index 0000000000000000000000000000000000000000..02d3fd5833a6d146f520ba1737299b1ae31c3160
--- /dev/null
+++ b/src/captioning/utils/logging.py
@@ -0,0 +1,100 @@
+"""Structured logging setup.
+
+Why structlog instead of stdlib `logging`?
+ * Logs are *data*, not strings. structlog emits dicts that grafana/Datadog/
+ Better Stack can index without regex parsing.
+ * The same code path produces colourised pretty logs in dev and JSON logs
+ in prod, controlled by ``APP_ENV``. Grep the same fields in either mode.
+ * Bound context (request IDs, model versions) propagates automatically.
+
+Usage:
+ >>> from captioning.utils.logging import configure_logging, get_logger
+ >>> configure_logging()
+ >>> log = get_logger(__name__)
+ >>> log.info("training started", epoch=1, batch_size=64)
+"""
+
+from __future__ import annotations
+
+import logging
+import os
+import sys
+from typing import Any
+
+import structlog
+
+_CONFIGURED = False
+
+
+def _resolve_level(level: str | int | None) -> int:
+ """Coerce a log-level argument (or env default) to a numeric level.
+
+ Why this helper exists:
+ ``logging.getLevelName`` is *bidirectional* — it returns ``int`` for
+ known names and ``str`` for unknown ones (e.g. ``"Level FOO"``). That
+ union return type defeats type narrowing and would be passed straight
+ through to ``structlog.make_filtering_bound_logger``, which requires
+ ``int``. We resolve once here, fall back to ``INFO`` on unknown
+ names, and return a guaranteed ``int``.
+ """
+ if level is None:
+ level = os.environ.get("LOG_LEVEL", "INFO")
+ if isinstance(level, int):
+ return level
+ resolved = logging.getLevelName(level.upper())
+ return resolved if isinstance(resolved, int) else logging.INFO
+
+
+def configure_logging(level: str | int | None = None, json_logs: bool | None = None) -> None:
+ """Initialise structlog. Idempotent — calling twice has no effect.
+
+ Args:
+ level: Log level name (``"INFO"``) or numeric value. Defaults to env
+ ``LOG_LEVEL`` or ``INFO``.
+ json_logs: If True, render JSON; if False, render pretty colourised.
+ Defaults to True when ``APP_ENV=production``, else False.
+ """
+ global _CONFIGURED
+ if _CONFIGURED:
+ return
+
+ level_int = _resolve_level(level)
+ if json_logs is None:
+ json_logs = os.environ.get("APP_ENV", "development").lower() == "production"
+
+ logging.basicConfig(
+ format="%(message)s",
+ stream=sys.stdout,
+ level=level_int,
+ )
+
+ timestamper = structlog.processors.TimeStamper(fmt="iso", utc=True)
+ shared_processors: list[Any] = [
+ structlog.contextvars.merge_contextvars,
+ structlog.stdlib.add_log_level,
+ structlog.stdlib.add_logger_name,
+ timestamper,
+ structlog.processors.StackInfoRenderer(),
+ structlog.processors.format_exc_info,
+ ]
+ renderer: Any = (
+ structlog.processors.JSONRenderer()
+ if json_logs
+ else structlog.dev.ConsoleRenderer(colors=True)
+ )
+
+ structlog.configure(
+ processors=[*shared_processors, renderer],
+ wrapper_class=structlog.make_filtering_bound_logger(level_int),
+ context_class=dict,
+ logger_factory=structlog.stdlib.LoggerFactory(),
+ cache_logger_on_first_use=True,
+ )
+ _CONFIGURED = True
+
+
+def get_logger(name: str | None = None) -> structlog.stdlib.BoundLogger:
+ """Return a logger bound to ``name`` (typically ``__name__``)."""
+ if not _CONFIGURED:
+ configure_logging()
+ return structlog.get_logger(name)
diff --git a/src/captioning/utils/seed.py b/src/captioning/utils/seed.py
new file mode 100644
index 0000000000000000000000000000000000000000..49fdfe2d04dca7dab77ce7358d68ee021020372d
--- /dev/null
+++ b/src/captioning/utils/seed.py
@@ -0,0 +1,49 @@
+"""Reproducibility helpers.
+
+Why this matters: the IEEE notebook's ``random.shuffle`` of image keys (cell 11)
+is non-deterministic without a seed, which means the same code can produce a
+different train/val split on every run — and therefore different BLEU. Pinning
+the seed makes results reproducible across machines and dates.
+"""
+
+from __future__ import annotations
+
+import os
+import random
+from typing import TYPE_CHECKING
+
+if TYPE_CHECKING: # pragma: no cover
+ pass
+
+
+def set_global_seed(seed: int) -> None:
+ """Seed Python, NumPy, and TensorFlow RNGs from a single integer.
+
+ TF's seeding has multiple layers (``tf.random.set_seed`` for graph-level,
+ ``os.environ['PYTHONHASHSEED']`` for hash randomisation, and op-level seeds
+ for individual ops). We set as many as practical without forcing TF's
+ deterministic mode (which can hurt training throughput by ~15%).
+
+ Args:
+ seed: Any non-negative integer.
+ """
+ if seed < 0:
+ raise ValueError(f"seed must be non-negative, got {seed}")
+
+ os.environ["PYTHONHASHSEED"] = str(seed)
+ random.seed(seed)
+
+ # Imported lazily so the utils package doesn't pull NumPy at import time
+ # for unrelated callers (e.g. config validation).
+ import numpy as np
+
+ np.random.seed(seed)
+
+ try:
+ import tensorflow as tf
+
+ tf.random.set_seed(seed)
+ tf.keras.utils.set_random_seed(seed)
+ except ImportError: # pragma: no cover
+ # TF is an optional dep at the *utility* layer; ML callers always have it.
+ pass