1):
+ gt_x = list(map(int, np.squeeze(gt[1])))
+ gt_y = list(map(int, np.squeeze(gt[3])))
+ for det_id, detection in enumerate(detections):
+ detection_orig = detection
+ detection = [float(x) for x in detection[0].split(',')]
+ detection = list(map(int, detection))
+ det_x = detection[0::2]
+ det_y = detection[1::2]
+ det_gt_iou = iod(det_x, det_y, gt_x, gt_y)
+ if det_gt_iou > threshold:
+ detections[det_id] = []
+
+ detections[:] = [item for item in detections if item != []]
+ return detections
+
+ def sigma_calculation(det_x, det_y, gt_x, gt_y):
+ """
+ sigma = inter_area / gt_area
+ """
+ return np.round((area_of_intersection(det_x, det_y, gt_x, gt_y) /
+ area(gt_x, gt_y)), 2)
+
+ def tau_calculation(det_x, det_y, gt_x, gt_y):
+ if area(det_x, det_y) == 0.0:
+ return 0
+ return np.round((area_of_intersection(det_x, det_y, gt_x, gt_y) /
+ area(det_x, det_y)), 2)
+
+ ##############################Initialization###################################
+ # global_sigma = []
+ # global_tau = []
+ # global_pred_str = []
+ # global_gt_str = []
+ ###############################################################################
+
+ for input_id in range(allInputs):
+ if (input_id != '.DS_Store') and (input_id != 'Pascal_result.txt') and (
+ input_id != 'Pascal_result_curved.txt') and (input_id != 'Pascal_result_non_curved.txt') and (
+ input_id != 'Deteval_result.txt') and (input_id != 'Deteval_result_curved.txt') \
+ and (input_id != 'Deteval_result_non_curved.txt'):
+ detections = input_reading_mod(pred_dict)
+ groundtruths = gt_reading_mod(gt_dir)
+ detections = detection_filtering(
+ detections,
+ groundtruths) # filters detections overlapping with DC area
+ dc_id = []
+ for i in range(len(groundtruths)):
+ if groundtruths[i][5] == '#':
+ dc_id.append(i)
+ cnt = 0
+ for a in dc_id:
+ num = a - cnt
+ del groundtruths[num]
+ cnt += 1
+
+ local_sigma_table = np.zeros((len(groundtruths), len(detections)))
+ local_tau_table = np.zeros((len(groundtruths), len(detections)))
+ local_pred_str = {}
+ local_gt_str = {}
+
+ for gt_id, gt in enumerate(groundtruths):
+ if len(detections) > 0:
+ for det_id, detection in enumerate(detections):
+ detection_orig = detection
+ detection = [float(x) for x in detection[0].split(',')]
+ detection = list(map(int, detection))
+ pred_seq_str = detection_orig[1].strip()
+ det_x = detection[0::2]
+ det_y = detection[1::2]
+ gt_x = list(map(int, np.squeeze(gt[1])))
+ gt_y = list(map(int, np.squeeze(gt[3])))
+ gt_seq_str = str(gt[4].tolist()[0])
+
+ local_sigma_table[gt_id, det_id] = sigma_calculation(
+ det_x, det_y, gt_x, gt_y)
+ local_tau_table[gt_id, det_id] = tau_calculation(
+ det_x, det_y, gt_x, gt_y)
+ local_pred_str[det_id] = pred_seq_str
+ local_gt_str[gt_id] = gt_seq_str
+
+ global_sigma = local_sigma_table
+ global_tau = local_tau_table
+ global_pred_str = local_pred_str
+ global_gt_str = local_gt_str
+
+ single_data = {}
+ single_data['sigma'] = global_sigma
+ single_data['global_tau'] = global_tau
+ single_data['global_pred_str'] = global_pred_str
+ single_data['global_gt_str'] = global_gt_str
+ return single_data
+
+
+def get_socre_B(gt_dir, img_id, pred_dict):
+ allInputs = 1
+
+ def input_reading_mod(pred_dict):
+ """This helper reads input from txt files"""
+ det = []
+ n = len(pred_dict)
+ for i in range(n):
+ points = pred_dict[i]['points']
+ text = pred_dict[i]['texts']
+ point = ",".join(map(str, points.reshape(-1, )))
+ det.append([point, text])
+ return det
+
+ def gt_reading_mod(gt_dir, gt_id):
+ gt = io.loadmat('%s/poly_gt_img%s.mat' % (gt_dir, gt_id))
+ gt = gt['polygt']
+ return gt
+
+ def detection_filtering(detections, groundtruths, threshold=0.5):
+ for gt_id, gt in enumerate(groundtruths):
+ if (gt[5] == '#') and (gt[1].shape[1] > 1):
+ gt_x = list(map(int, np.squeeze(gt[1])))
+ gt_y = list(map(int, np.squeeze(gt[3])))
+ for det_id, detection in enumerate(detections):
+ detection_orig = detection
+ detection = [float(x) for x in detection[0].split(',')]
+ detection = list(map(int, detection))
+ det_x = detection[0::2]
+ det_y = detection[1::2]
+ det_gt_iou = iod(det_x, det_y, gt_x, gt_y)
+ if det_gt_iou > threshold:
+ detections[det_id] = []
+
+ detections[:] = [item for item in detections if item != []]
+ return detections
+
+ def sigma_calculation(det_x, det_y, gt_x, gt_y):
+ """
+ sigma = inter_area / gt_area
+ """
+ return np.round((area_of_intersection(det_x, det_y, gt_x, gt_y) /
+ area(gt_x, gt_y)), 2)
+
+ def tau_calculation(det_x, det_y, gt_x, gt_y):
+ if area(det_x, det_y) == 0.0:
+ return 0
+ return np.round((area_of_intersection(det_x, det_y, gt_x, gt_y) /
+ area(det_x, det_y)), 2)
+
+ ##############################Initialization###################################
+ # global_sigma = []
+ # global_tau = []
+ # global_pred_str = []
+ # global_gt_str = []
+ ###############################################################################
+
+ for input_id in range(allInputs):
+ if (input_id != '.DS_Store') and (input_id != 'Pascal_result.txt') and (
+ input_id != 'Pascal_result_curved.txt') and (input_id != 'Pascal_result_non_curved.txt') and (
+ input_id != 'Deteval_result.txt') and (input_id != 'Deteval_result_curved.txt') \
+ and (input_id != 'Deteval_result_non_curved.txt'):
+ detections = input_reading_mod(pred_dict)
+ groundtruths = gt_reading_mod(gt_dir, img_id).tolist()
+ detections = detection_filtering(
+ detections,
+ groundtruths) # filters detections overlapping with DC area
+ dc_id = []
+ for i in range(len(groundtruths)):
+ if groundtruths[i][5] == '#':
+ dc_id.append(i)
+ cnt = 0
+ for a in dc_id:
+ num = a - cnt
+ del groundtruths[num]
+ cnt += 1
+
+ local_sigma_table = np.zeros((len(groundtruths), len(detections)))
+ local_tau_table = np.zeros((len(groundtruths), len(detections)))
+ local_pred_str = {}
+ local_gt_str = {}
+
+ for gt_id, gt in enumerate(groundtruths):
+ if len(detections) > 0:
+ for det_id, detection in enumerate(detections):
+ detection_orig = detection
+ detection = [float(x) for x in detection[0].split(',')]
+ detection = list(map(int, detection))
+ pred_seq_str = detection_orig[1].strip()
+ det_x = detection[0::2]
+ det_y = detection[1::2]
+ gt_x = list(map(int, np.squeeze(gt[1])))
+ gt_y = list(map(int, np.squeeze(gt[3])))
+ gt_seq_str = str(gt[4].tolist()[0])
+
+ local_sigma_table[gt_id, det_id] = sigma_calculation(
+ det_x, det_y, gt_x, gt_y)
+ local_tau_table[gt_id, det_id] = tau_calculation(
+ det_x, det_y, gt_x, gt_y)
+ local_pred_str[det_id] = pred_seq_str
+ local_gt_str[gt_id] = gt_seq_str
+
+ global_sigma = local_sigma_table
+ global_tau = local_tau_table
+ global_pred_str = local_pred_str
+ global_gt_str = local_gt_str
+
+ single_data = {}
+ single_data['sigma'] = global_sigma
+ single_data['global_tau'] = global_tau
+ single_data['global_pred_str'] = global_pred_str
+ single_data['global_gt_str'] = global_gt_str
+ return single_data
+
+
+def get_score_C(gt_label, text, pred_bboxes):
+ """
+ get score for CentripetalText (CT) prediction.
+ """
+ check_install("Polygon", "Polygon3")
+ import Polygon as plg
+
+ def gt_reading_mod(gt_label, text):
+ """This helper reads groundtruths from mat files"""
+ groundtruths = []
+ nbox = len(gt_label)
+ for i in range(nbox):
+ label = {"transcription": text[i][0], "points": gt_label[i].numpy()}
+ groundtruths.append(label)
+
+ return groundtruths
+
+ def get_union(pD, pG):
+ areaA = pD.area()
+ areaB = pG.area()
+ return areaA + areaB - get_intersection(pD, pG)
+
+ def get_intersection(pD, pG):
+ pInt = pD & pG
+ if len(pInt) == 0:
+ return 0
+ return pInt.area()
+
+ def detection_filtering(detections, groundtruths, threshold=0.5):
+ for gt in groundtruths:
+ point_num = gt['points'].shape[1] // 2
+ if gt['transcription'] == '###' and (point_num > 1):
+ gt_p = np.array(gt['points']).reshape(point_num,
+ 2).astype('int32')
+ gt_p = plg.Polygon(gt_p)
+
+ for det_id, detection in enumerate(detections):
+ det_y = detection[0::2]
+ det_x = detection[1::2]
+
+ det_p = np.concatenate((np.array(det_x), np.array(det_y)))
+ det_p = det_p.reshape(2, -1).transpose()
+ det_p = plg.Polygon(det_p)
+
+ try:
+ det_gt_iou = get_intersection(det_p,
+ gt_p) / det_p.area()
+ except:
+ print(det_x, det_y, gt_p)
+ if det_gt_iou > threshold:
+ detections[det_id] = []
+
+ detections[:] = [item for item in detections if item != []]
+ return detections
+
+ def sigma_calculation(det_p, gt_p):
+ """
+ sigma = inter_area / gt_area
+ """
+ if gt_p.area() == 0.:
+ return 0
+ return get_intersection(det_p, gt_p) / gt_p.area()
+
+ def tau_calculation(det_p, gt_p):
+ """
+ tau = inter_area / det_area
+ """
+ if det_p.area() == 0.:
+ return 0
+ return get_intersection(det_p, gt_p) / det_p.area()
+
+ detections = []
+
+ for item in pred_bboxes:
+ detections.append(item[:, ::-1].reshape(-1))
+
+ groundtruths = gt_reading_mod(gt_label, text)
+
+ detections = detection_filtering(
+ detections, groundtruths) # filters detections overlapping with DC area
+
+ for idx in range(len(groundtruths) - 1, -1, -1):
+ #NOTE: source code use 'orin' to indicate '#', here we use 'anno',
+ # which may cause slight drop in fscore, about 0.12
+ if groundtruths[idx]['transcription'] == '###':
+ groundtruths.pop(idx)
+
+ local_sigma_table = np.zeros((len(groundtruths), len(detections)))
+ local_tau_table = np.zeros((len(groundtruths), len(detections)))
+
+ for gt_id, gt in enumerate(groundtruths):
+ if len(detections) > 0:
+ for det_id, detection in enumerate(detections):
+ point_num = gt['points'].shape[1] // 2
+
+ gt_p = np.array(gt['points']).reshape(point_num,
+ 2).astype('int32')
+ gt_p = plg.Polygon(gt_p)
+
+ det_y = detection[0::2]
+ det_x = detection[1::2]
+
+ det_p = np.concatenate((np.array(det_x), np.array(det_y)))
+
+ det_p = det_p.reshape(2, -1).transpose()
+ det_p = plg.Polygon(det_p)
+
+ local_sigma_table[gt_id, det_id] = sigma_calculation(det_p,
+ gt_p)
+ local_tau_table[gt_id, det_id] = tau_calculation(det_p, gt_p)
+
+ data = {}
+ data['sigma'] = local_sigma_table
+ data['global_tau'] = local_tau_table
+ data['global_pred_str'] = ''
+ data['global_gt_str'] = ''
+ return data
+
+
+def combine_results(all_data, rec_flag=True):
+ tr = 0.7
+ tp = 0.6
+ fsc_k = 0.8
+ k = 2
+ global_sigma = []
+ global_tau = []
+ global_pred_str = []
+ global_gt_str = []
+
+ for data in all_data:
+ global_sigma.append(data['sigma'])
+ global_tau.append(data['global_tau'])
+ global_pred_str.append(data['global_pred_str'])
+ global_gt_str.append(data['global_gt_str'])
+
+ global_accumulative_recall = 0
+ global_accumulative_precision = 0
+ total_num_gt = 0
+ total_num_det = 0
+ hit_str_count = 0
+ hit_count = 0
+
+ def one_to_one(local_sigma_table, local_tau_table,
+ local_accumulative_recall, local_accumulative_precision,
+ global_accumulative_recall, global_accumulative_precision,
+ gt_flag, det_flag, idy, rec_flag):
+ hit_str_num = 0
+ for gt_id in range(num_gt):
+ gt_matching_qualified_sigma_candidates = np.where(
+ local_sigma_table[gt_id, :] > tr)
+ gt_matching_num_qualified_sigma_candidates = gt_matching_qualified_sigma_candidates[
+ 0].shape[0]
+ gt_matching_qualified_tau_candidates = np.where(
+ local_tau_table[gt_id, :] > tp)
+ gt_matching_num_qualified_tau_candidates = gt_matching_qualified_tau_candidates[
+ 0].shape[0]
+
+ det_matching_qualified_sigma_candidates = np.where(
+ local_sigma_table[:, gt_matching_qualified_sigma_candidates[0]]
+ > tr)
+ det_matching_num_qualified_sigma_candidates = det_matching_qualified_sigma_candidates[
+ 0].shape[0]
+ det_matching_qualified_tau_candidates = np.where(
+ local_tau_table[:, gt_matching_qualified_tau_candidates[0]] >
+ tp)
+ det_matching_num_qualified_tau_candidates = det_matching_qualified_tau_candidates[
+ 0].shape[0]
+
+ if (gt_matching_num_qualified_sigma_candidates == 1) and (gt_matching_num_qualified_tau_candidates == 1) and \
+ (det_matching_num_qualified_sigma_candidates == 1) and (
+ det_matching_num_qualified_tau_candidates == 1):
+ global_accumulative_recall = global_accumulative_recall + 1.0
+ global_accumulative_precision = global_accumulative_precision + 1.0
+ local_accumulative_recall = local_accumulative_recall + 1.0
+ local_accumulative_precision = local_accumulative_precision + 1.0
+
+ gt_flag[0, gt_id] = 1
+ matched_det_id = np.where(local_sigma_table[gt_id, :] > tr)
+ # recg start
+ if rec_flag:
+ gt_str_cur = global_gt_str[idy][gt_id]
+ pred_str_cur = global_pred_str[idy][matched_det_id[0]
+ .tolist()[0]]
+ if pred_str_cur == gt_str_cur:
+ hit_str_num += 1
+ else:
+ if pred_str_cur.lower() == gt_str_cur.lower():
+ hit_str_num += 1
+ # recg end
+ det_flag[0, matched_det_id] = 1
+ return local_accumulative_recall, local_accumulative_precision, global_accumulative_recall, global_accumulative_precision, gt_flag, det_flag, hit_str_num
+
+ def one_to_many(local_sigma_table, local_tau_table,
+ local_accumulative_recall, local_accumulative_precision,
+ global_accumulative_recall, global_accumulative_precision,
+ gt_flag, det_flag, idy, rec_flag):
+ hit_str_num = 0
+ for gt_id in range(num_gt):
+ # skip the following if the groundtruth was matched
+ if gt_flag[0, gt_id] > 0:
+ continue
+
+ non_zero_in_sigma = np.where(local_sigma_table[gt_id, :] > 0)
+ num_non_zero_in_sigma = non_zero_in_sigma[0].shape[0]
+
+ if num_non_zero_in_sigma >= k:
+ ####search for all detections that overlaps with this groundtruth
+ qualified_tau_candidates = np.where((local_tau_table[
+ gt_id, :] >= tp) & (det_flag[0, :] == 0))
+ num_qualified_tau_candidates = qualified_tau_candidates[
+ 0].shape[0]
+
+ if num_qualified_tau_candidates == 1:
+ if ((local_tau_table[gt_id, qualified_tau_candidates] >= tp)
+ and
+ (local_sigma_table[gt_id, qualified_tau_candidates] >=
+ tr)):
+ # became an one-to-one case
+ global_accumulative_recall = global_accumulative_recall + 1.0
+ global_accumulative_precision = global_accumulative_precision + 1.0
+ local_accumulative_recall = local_accumulative_recall + 1.0
+ local_accumulative_precision = local_accumulative_precision + 1.0
+
+ gt_flag[0, gt_id] = 1
+ det_flag[0, qualified_tau_candidates] = 1
+ # recg start
+ if rec_flag:
+ gt_str_cur = global_gt_str[idy][gt_id]
+ pred_str_cur = global_pred_str[idy][
+ qualified_tau_candidates[0].tolist()[0]]
+ if pred_str_cur == gt_str_cur:
+ hit_str_num += 1
+ else:
+ if pred_str_cur.lower() == gt_str_cur.lower():
+ hit_str_num += 1
+ # recg end
+ elif (np.sum(local_sigma_table[gt_id, qualified_tau_candidates])
+ >= tr):
+ gt_flag[0, gt_id] = 1
+ det_flag[0, qualified_tau_candidates] = 1
+ # recg start
+ if rec_flag:
+ gt_str_cur = global_gt_str[idy][gt_id]
+ pred_str_cur = global_pred_str[idy][
+ qualified_tau_candidates[0].tolist()[0]]
+ if pred_str_cur == gt_str_cur:
+ hit_str_num += 1
+ else:
+ if pred_str_cur.lower() == gt_str_cur.lower():
+ hit_str_num += 1
+ # recg end
+
+ global_accumulative_recall = global_accumulative_recall + fsc_k
+ global_accumulative_precision = global_accumulative_precision + num_qualified_tau_candidates * fsc_k
+
+ local_accumulative_recall = local_accumulative_recall + fsc_k
+ local_accumulative_precision = local_accumulative_precision + num_qualified_tau_candidates * fsc_k
+
+ return local_accumulative_recall, local_accumulative_precision, global_accumulative_recall, global_accumulative_precision, gt_flag, det_flag, hit_str_num
+
+ def many_to_one(local_sigma_table, local_tau_table,
+ local_accumulative_recall, local_accumulative_precision,
+ global_accumulative_recall, global_accumulative_precision,
+ gt_flag, det_flag, idy, rec_flag):
+ hit_str_num = 0
+ for det_id in range(num_det):
+ # skip the following if the detection was matched
+ if det_flag[0, det_id] > 0:
+ continue
+
+ non_zero_in_tau = np.where(local_tau_table[:, det_id] > 0)
+ num_non_zero_in_tau = non_zero_in_tau[0].shape[0]
+
+ if num_non_zero_in_tau >= k:
+ ####search for all detections that overlaps with this groundtruth
+ qualified_sigma_candidates = np.where((
+ local_sigma_table[:, det_id] >= tp) & (gt_flag[0, :] == 0))
+ num_qualified_sigma_candidates = qualified_sigma_candidates[
+ 0].shape[0]
+
+ if num_qualified_sigma_candidates == 1:
+ if ((local_tau_table[qualified_sigma_candidates, det_id] >=
+ tp) and
+ (local_sigma_table[qualified_sigma_candidates, det_id]
+ >= tr)):
+ # became an one-to-one case
+ global_accumulative_recall = global_accumulative_recall + 1.0
+ global_accumulative_precision = global_accumulative_precision + 1.0
+ local_accumulative_recall = local_accumulative_recall + 1.0
+ local_accumulative_precision = local_accumulative_precision + 1.0
+
+ gt_flag[0, qualified_sigma_candidates] = 1
+ det_flag[0, det_id] = 1
+ # recg start
+ if rec_flag:
+ pred_str_cur = global_pred_str[idy][det_id]
+ gt_len = len(qualified_sigma_candidates[0])
+ for idx in range(gt_len):
+ ele_gt_id = qualified_sigma_candidates[
+ 0].tolist()[idx]
+ if ele_gt_id not in global_gt_str[idy]:
+ continue
+ gt_str_cur = global_gt_str[idy][ele_gt_id]
+ if pred_str_cur == gt_str_cur:
+ hit_str_num += 1
+ break
+ else:
+ if pred_str_cur.lower() == gt_str_cur.lower(
+ ):
+ hit_str_num += 1
+ break
+ # recg end
+ elif (np.sum(local_tau_table[qualified_sigma_candidates,
+ det_id]) >= tp):
+ det_flag[0, det_id] = 1
+ gt_flag[0, qualified_sigma_candidates] = 1
+ # recg start
+ if rec_flag:
+ pred_str_cur = global_pred_str[idy][det_id]
+ gt_len = len(qualified_sigma_candidates[0])
+ for idx in range(gt_len):
+ ele_gt_id = qualified_sigma_candidates[0].tolist()[
+ idx]
+ if ele_gt_id not in global_gt_str[idy]:
+ continue
+ gt_str_cur = global_gt_str[idy][ele_gt_id]
+ if pred_str_cur == gt_str_cur:
+ hit_str_num += 1
+ break
+ else:
+ if pred_str_cur.lower() == gt_str_cur.lower():
+ hit_str_num += 1
+ break
+ # recg end
+
+ global_accumulative_recall = global_accumulative_recall + num_qualified_sigma_candidates * fsc_k
+ global_accumulative_precision = global_accumulative_precision + fsc_k
+
+ local_accumulative_recall = local_accumulative_recall + num_qualified_sigma_candidates * fsc_k
+ local_accumulative_precision = local_accumulative_precision + fsc_k
+ return local_accumulative_recall, local_accumulative_precision, global_accumulative_recall, global_accumulative_precision, gt_flag, det_flag, hit_str_num
+
+ for idx in range(len(global_sigma)):
+ local_sigma_table = np.array(global_sigma[idx])
+ local_tau_table = global_tau[idx]
+
+ num_gt = local_sigma_table.shape[0]
+ num_det = local_sigma_table.shape[1]
+
+ total_num_gt = total_num_gt + num_gt
+ total_num_det = total_num_det + num_det
+
+ local_accumulative_recall = 0
+ local_accumulative_precision = 0
+ gt_flag = np.zeros((1, num_gt))
+ det_flag = np.zeros((1, num_det))
+
+ #######first check for one-to-one case##########
+ local_accumulative_recall, local_accumulative_precision, global_accumulative_recall, global_accumulative_precision, \
+ gt_flag, det_flag, hit_str_num = one_to_one(local_sigma_table, local_tau_table,
+ local_accumulative_recall, local_accumulative_precision,
+ global_accumulative_recall, global_accumulative_precision,
+ gt_flag, det_flag, idx, rec_flag)
+
+ hit_str_count += hit_str_num
+ #######then check for one-to-many case##########
+ local_accumulative_recall, local_accumulative_precision, global_accumulative_recall, global_accumulative_precision, \
+ gt_flag, det_flag, hit_str_num = one_to_many(local_sigma_table, local_tau_table,
+ local_accumulative_recall, local_accumulative_precision,
+ global_accumulative_recall, global_accumulative_precision,
+ gt_flag, det_flag, idx, rec_flag)
+ hit_str_count += hit_str_num
+ #######then check for many-to-one case##########
+ local_accumulative_recall, local_accumulative_precision, global_accumulative_recall, global_accumulative_precision, \
+ gt_flag, det_flag, hit_str_num = many_to_one(local_sigma_table, local_tau_table,
+ local_accumulative_recall, local_accumulative_precision,
+ global_accumulative_recall, global_accumulative_precision,
+ gt_flag, det_flag, idx, rec_flag)
+ hit_str_count += hit_str_num
+
+ try:
+ recall = global_accumulative_recall / total_num_gt
+ except ZeroDivisionError:
+ recall = 0
+
+ try:
+ precision = global_accumulative_precision / total_num_det
+ except ZeroDivisionError:
+ precision = 0
+
+ try:
+ f_score = 2 * precision * recall / (precision + recall)
+ except ZeroDivisionError:
+ f_score = 0
+
+ try:
+ seqerr = 1 - float(hit_str_count) / global_accumulative_recall
+ except ZeroDivisionError:
+ seqerr = 1
+
+ try:
+ recall_e2e = float(hit_str_count) / total_num_gt
+ except ZeroDivisionError:
+ recall_e2e = 0
+
+ try:
+ precision_e2e = float(hit_str_count) / total_num_det
+ except ZeroDivisionError:
+ precision_e2e = 0
+
+ try:
+ f_score_e2e = 2 * precision_e2e * recall_e2e / (
+ precision_e2e + recall_e2e)
+ except ZeroDivisionError:
+ f_score_e2e = 0
+
+ final = {
+ 'total_num_gt': total_num_gt,
+ 'total_num_det': total_num_det,
+ 'global_accumulative_recall': global_accumulative_recall,
+ 'hit_str_count': hit_str_count,
+ 'recall': recall,
+ 'precision': precision,
+ 'f_score': f_score,
+ 'seqerr': seqerr,
+ 'recall_e2e': recall_e2e,
+ 'precision_e2e': precision_e2e,
+ 'f_score_e2e': f_score_e2e
+ }
+ return final
diff --git a/ocr-studio/PaddleOCR/ppocr/utils/e2e_metric/polygon_fast.py b/ocr-studio/PaddleOCR/ppocr/utils/e2e_metric/polygon_fast.py
new file mode 100644
index 0000000000000000000000000000000000000000..81c9ad70675bb37a95968283b6dc6f42f709df27
--- /dev/null
+++ b/ocr-studio/PaddleOCR/ppocr/utils/e2e_metric/polygon_fast.py
@@ -0,0 +1,83 @@
+# Copyright (c) 2021 PaddlePaddle Authors. All Rights Reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+import numpy as np
+from shapely.geometry import Polygon
+"""
+:param det_x: [1, N] Xs of detection's vertices
+:param det_y: [1, N] Ys of detection's vertices
+:param gt_x: [1, N] Xs of groundtruth's vertices
+:param gt_y: [1, N] Ys of groundtruth's vertices
+
+##############
+All the calculation of 'AREA' in this script is handled by:
+1) First generating a binary mask with the polygon area filled up with 1's
+2) Summing up all the 1's
+"""
+
+
+def area(x, y):
+ polygon = Polygon(np.stack([x, y], axis=1))
+ return float(polygon.area)
+
+
+def approx_area_of_intersection(det_x, det_y, gt_x, gt_y):
+ """
+ This helper determine if both polygons are intersecting with each others with an approximation method.
+ Area of intersection represented by the minimum bounding rectangular [xmin, ymin, xmax, ymax]
+ """
+ det_ymax = np.max(det_y)
+ det_xmax = np.max(det_x)
+ det_ymin = np.min(det_y)
+ det_xmin = np.min(det_x)
+
+ gt_ymax = np.max(gt_y)
+ gt_xmax = np.max(gt_x)
+ gt_ymin = np.min(gt_y)
+ gt_xmin = np.min(gt_x)
+
+ all_min_ymax = np.minimum(det_ymax, gt_ymax)
+ all_max_ymin = np.maximum(det_ymin, gt_ymin)
+
+ intersect_heights = np.maximum(0.0, (all_min_ymax - all_max_ymin))
+
+ all_min_xmax = np.minimum(det_xmax, gt_xmax)
+ all_max_xmin = np.maximum(det_xmin, gt_xmin)
+ intersect_widths = np.maximum(0.0, (all_min_xmax - all_max_xmin))
+
+ return intersect_heights * intersect_widths
+
+
+def area_of_intersection(det_x, det_y, gt_x, gt_y):
+ p1 = Polygon(np.stack([det_x, det_y], axis=1)).buffer(0)
+ p2 = Polygon(np.stack([gt_x, gt_y], axis=1)).buffer(0)
+ return float(p1.intersection(p2).area)
+
+
+def area_of_union(det_x, det_y, gt_x, gt_y):
+ p1 = Polygon(np.stack([det_x, det_y], axis=1)).buffer(0)
+ p2 = Polygon(np.stack([gt_x, gt_y], axis=1)).buffer(0)
+ return float(p1.union(p2).area)
+
+
+def iou(det_x, det_y, gt_x, gt_y):
+ return area_of_intersection(det_x, det_y, gt_x, gt_y) / (
+ area_of_union(det_x, det_y, gt_x, gt_y) + 1.0)
+
+
+def iod(det_x, det_y, gt_x, gt_y):
+ """
+ This helper determine the fraction of intersection area over detection area
+ """
+ return area_of_intersection(det_x, det_y, gt_x, gt_y) / (
+ area(det_x, det_y) + 1.0)
diff --git a/ocr-studio/PaddleOCR/ppocr/utils/e2e_utils/extract_batchsize.py b/ocr-studio/PaddleOCR/ppocr/utils/e2e_utils/extract_batchsize.py
new file mode 100644
index 0000000000000000000000000000000000000000..e99a833ea76a81e02d39b16fe1a01e22f15bf3a4
--- /dev/null
+++ b/ocr-studio/PaddleOCR/ppocr/utils/e2e_utils/extract_batchsize.py
@@ -0,0 +1,87 @@
+import paddle
+import numpy as np
+import copy
+
+
+def org_tcl_rois(batch_size, pos_lists, pos_masks, label_lists, tcl_bs):
+ """
+ """
+ pos_lists_, pos_masks_, label_lists_ = [], [], []
+ img_bs = batch_size
+ ngpu = int(batch_size / img_bs)
+ img_ids = np.array(pos_lists, dtype=np.int32)[:, 0, 0].copy()
+ pos_lists_split, pos_masks_split, label_lists_split = [], [], []
+ for i in range(ngpu):
+ pos_lists_split.append([])
+ pos_masks_split.append([])
+ label_lists_split.append([])
+
+ for i in range(img_ids.shape[0]):
+ img_id = img_ids[i]
+ gpu_id = int(img_id / img_bs)
+ img_id = img_id % img_bs
+ pos_list = pos_lists[i].copy()
+ pos_list[:, 0] = img_id
+ pos_lists_split[gpu_id].append(pos_list)
+ pos_masks_split[gpu_id].append(pos_masks[i].copy())
+ label_lists_split[gpu_id].append(copy.deepcopy(label_lists[i]))
+ # repeat or delete
+ for i in range(ngpu):
+ vp_len = len(pos_lists_split[i])
+ if vp_len <= tcl_bs:
+ for j in range(0, tcl_bs - vp_len):
+ pos_list = pos_lists_split[i][j].copy()
+ pos_lists_split[i].append(pos_list)
+ pos_mask = pos_masks_split[i][j].copy()
+ pos_masks_split[i].append(pos_mask)
+ label_list = copy.deepcopy(label_lists_split[i][j])
+ label_lists_split[i].append(label_list)
+ else:
+ for j in range(0, vp_len - tcl_bs):
+ c_len = len(pos_lists_split[i])
+ pop_id = np.random.permutation(c_len)[0]
+ pos_lists_split[i].pop(pop_id)
+ pos_masks_split[i].pop(pop_id)
+ label_lists_split[i].pop(pop_id)
+ # merge
+ for i in range(ngpu):
+ pos_lists_.extend(pos_lists_split[i])
+ pos_masks_.extend(pos_masks_split[i])
+ label_lists_.extend(label_lists_split[i])
+ return pos_lists_, pos_masks_, label_lists_
+
+
+def pre_process(label_list, pos_list, pos_mask, max_text_length, max_text_nums,
+ pad_num, tcl_bs):
+ label_list = label_list.numpy()
+ batch, _, _, _ = label_list.shape
+ pos_list = pos_list.numpy()
+ pos_mask = pos_mask.numpy()
+ pos_list_t = []
+ pos_mask_t = []
+ label_list_t = []
+ for i in range(batch):
+ for j in range(max_text_nums):
+ if pos_mask[i, j].any():
+ pos_list_t.append(pos_list[i][j])
+ pos_mask_t.append(pos_mask[i][j])
+ label_list_t.append(label_list[i][j])
+ pos_list, pos_mask, label_list = org_tcl_rois(batch, pos_list_t, pos_mask_t,
+ label_list_t, tcl_bs)
+ label = []
+ tt = [l.tolist() for l in label_list]
+ for i in range(tcl_bs):
+ k = 0
+ for j in range(max_text_length):
+ if tt[i][j][0] != pad_num:
+ k += 1
+ else:
+ break
+ label.append(k)
+ label = paddle.to_tensor(label)
+ label = paddle.cast(label, dtype='int64')
+ pos_list = paddle.to_tensor(pos_list)
+ pos_mask = paddle.to_tensor(pos_mask)
+ label_list = paddle.squeeze(paddle.to_tensor(label_list), axis=2)
+ label_list = paddle.cast(label_list, dtype='int32')
+ return pos_list, pos_mask, label_list, label
diff --git a/ocr-studio/PaddleOCR/ppocr/utils/e2e_utils/extract_textpoint_fast.py b/ocr-studio/PaddleOCR/ppocr/utils/e2e_utils/extract_textpoint_fast.py
new file mode 100644
index 0000000000000000000000000000000000000000..a85b8e78ead00e64630b57400b9e5141eb0181a8
--- /dev/null
+++ b/ocr-studio/PaddleOCR/ppocr/utils/e2e_utils/extract_textpoint_fast.py
@@ -0,0 +1,492 @@
+# Copyright (c) 2021 PaddlePaddle Authors. All Rights Reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Contains various CTC decoders."""
+from __future__ import absolute_import
+from __future__ import division
+from __future__ import print_function
+
+import cv2
+import math
+
+import numpy as np
+from itertools import groupby
+from skimage.morphology._skeletonize import thin
+
+
+def get_dict(character_dict_path):
+ character_str = ""
+ with open(character_dict_path, "rb") as fin:
+ lines = fin.readlines()
+ for line in lines:
+ line = line.decode('utf-8').strip("\n").strip("\r\n")
+ character_str += line
+ dict_character = list(character_str)
+ return dict_character
+
+
+def softmax(logits):
+ """
+ logits: N x d
+ """
+ max_value = np.max(logits, axis=1, keepdims=True)
+ exp = np.exp(logits - max_value)
+ exp_sum = np.sum(exp, axis=1, keepdims=True)
+ dist = exp / exp_sum
+ return dist
+
+
+def get_keep_pos_idxs(labels, remove_blank=None):
+ """
+ Remove duplicate and get pos idxs of keep items.
+ The value of keep_blank should be [None, 95].
+ """
+ duplicate_len_list = []
+ keep_pos_idx_list = []
+ keep_char_idx_list = []
+ for k, v_ in groupby(labels):
+ current_len = len(list(v_))
+ if k != remove_blank:
+ current_idx = int(sum(duplicate_len_list) + current_len // 2)
+ keep_pos_idx_list.append(current_idx)
+ keep_char_idx_list.append(k)
+ duplicate_len_list.append(current_len)
+ return keep_char_idx_list, keep_pos_idx_list
+
+
+def remove_blank(labels, blank=0):
+ new_labels = [x for x in labels if x != blank]
+ return new_labels
+
+
+def insert_blank(labels, blank=0):
+ new_labels = [blank]
+ for l in labels:
+ new_labels += [l, blank]
+ return new_labels
+
+
+def ctc_greedy_decoder(probs_seq, blank=95, keep_blank_in_idxs=True):
+ """
+ CTC greedy (best path) decoder.
+ """
+ raw_str = np.argmax(np.array(probs_seq), axis=1)
+ remove_blank_in_pos = None if keep_blank_in_idxs else blank
+ dedup_str, keep_idx_list = get_keep_pos_idxs(
+ raw_str, remove_blank=remove_blank_in_pos)
+ dst_str = remove_blank(dedup_str, blank=blank)
+ return dst_str, keep_idx_list
+
+
+def instance_ctc_greedy_decoder(gather_info,
+ logits_map,
+ pts_num=4,
+ point_gather_mode=None):
+ _, _, C = logits_map.shape
+ if point_gather_mode == 'align':
+ insert_num = 0
+ gather_info = np.array(gather_info)
+ length = len(gather_info) - 1
+ for index in range(length):
+ stride_y = np.abs(gather_info[index + insert_num][0] - gather_info[
+ index + 1 + insert_num][0])
+ stride_x = np.abs(gather_info[index + insert_num][1] - gather_info[
+ index + 1 + insert_num][1])
+ max_points = int(max(stride_x, stride_y))
+ stride = (gather_info[index + insert_num] -
+ gather_info[index + 1 + insert_num]) / (max_points)
+ insert_num_temp = max_points - 1
+
+ for i in range(int(insert_num_temp)):
+ insert_value = gather_info[index + insert_num] - (i + 1
+ ) * stride
+ insert_index = index + i + 1 + insert_num
+ gather_info = np.insert(
+ gather_info, insert_index, insert_value, axis=0)
+ insert_num += insert_num_temp
+ gather_info = gather_info.tolist()
+ else:
+ pass
+ ys, xs = zip(*gather_info)
+ logits_seq = logits_map[list(ys), list(xs)]
+ probs_seq = logits_seq
+ labels = np.argmax(probs_seq, axis=1)
+ dst_str = [k for k, v_ in groupby(labels) if k != C - 1]
+ detal = len(gather_info) // (pts_num - 1)
+ keep_idx_list = [0] + [detal * (i + 1) for i in range(pts_num - 2)] + [-1]
+ keep_gather_list = [gather_info[idx] for idx in keep_idx_list]
+ return dst_str, keep_gather_list
+
+
+def ctc_decoder_for_image(gather_info_list,
+ logits_map,
+ Lexicon_Table,
+ pts_num=6,
+ point_gather_mode=None):
+ """
+ CTC decoder using multiple processes.
+ """
+ decoder_str = []
+ decoder_xys = []
+ for gather_info in gather_info_list:
+ if len(gather_info) < pts_num:
+ continue
+ dst_str, xys_list = instance_ctc_greedy_decoder(
+ gather_info,
+ logits_map,
+ pts_num=pts_num,
+ point_gather_mode=point_gather_mode)
+ dst_str_readable = ''.join([Lexicon_Table[idx] for idx in dst_str])
+ if len(dst_str_readable) < 2:
+ continue
+ decoder_str.append(dst_str_readable)
+ decoder_xys.append(xys_list)
+ return decoder_str, decoder_xys
+
+
+def sort_with_direction(pos_list, f_direction):
+ """
+ f_direction: h x w x 2
+ pos_list: [[y, x], [y, x], [y, x] ...]
+ """
+
+ def sort_part_with_direction(pos_list, point_direction):
+ pos_list = np.array(pos_list).reshape(-1, 2)
+ point_direction = np.array(point_direction).reshape(-1, 2)
+ average_direction = np.mean(point_direction, axis=0, keepdims=True)
+ pos_proj_leng = np.sum(pos_list * average_direction, axis=1)
+ sorted_list = pos_list[np.argsort(pos_proj_leng)].tolist()
+ sorted_direction = point_direction[np.argsort(pos_proj_leng)].tolist()
+ return sorted_list, sorted_direction
+
+ pos_list = np.array(pos_list).reshape(-1, 2)
+ point_direction = f_direction[pos_list[:, 0], pos_list[:, 1]] # x, y
+ point_direction = point_direction[:, ::-1] # x, y -> y, x
+ sorted_point, sorted_direction = sort_part_with_direction(pos_list,
+ point_direction)
+
+ point_num = len(sorted_point)
+ if point_num >= 16:
+ middle_num = point_num // 2
+ first_part_point = sorted_point[:middle_num]
+ first_point_direction = sorted_direction[:middle_num]
+ sorted_fist_part_point, sorted_fist_part_direction = sort_part_with_direction(
+ first_part_point, first_point_direction)
+
+ last_part_point = sorted_point[middle_num:]
+ last_point_direction = sorted_direction[middle_num:]
+ sorted_last_part_point, sorted_last_part_direction = sort_part_with_direction(
+ last_part_point, last_point_direction)
+ sorted_point = sorted_fist_part_point + sorted_last_part_point
+ sorted_direction = sorted_fist_part_direction + sorted_last_part_direction
+
+ return sorted_point, np.array(sorted_direction)
+
+
+def add_id(pos_list, image_id=0):
+ """
+ Add id for gather feature, for inference.
+ """
+ new_list = []
+ for item in pos_list:
+ new_list.append((image_id, item[0], item[1]))
+ return new_list
+
+
+def sort_and_expand_with_direction(pos_list, f_direction):
+ """
+ f_direction: h x w x 2
+ pos_list: [[y, x], [y, x], [y, x] ...]
+ """
+ h, w, _ = f_direction.shape
+ sorted_list, point_direction = sort_with_direction(pos_list, f_direction)
+
+ point_num = len(sorted_list)
+ sub_direction_len = max(point_num // 3, 2)
+ left_direction = point_direction[:sub_direction_len, :]
+ right_dirction = point_direction[point_num - sub_direction_len:, :]
+
+ left_average_direction = -np.mean(left_direction, axis=0, keepdims=True)
+ left_average_len = np.linalg.norm(left_average_direction)
+ left_start = np.array(sorted_list[0])
+ left_step = left_average_direction / (left_average_len + 1e-6)
+
+ right_average_direction = np.mean(right_dirction, axis=0, keepdims=True)
+ right_average_len = np.linalg.norm(right_average_direction)
+ right_step = right_average_direction / (right_average_len + 1e-6)
+ right_start = np.array(sorted_list[-1])
+
+ append_num = max(
+ int((left_average_len + right_average_len) / 2.0 * 0.15), 1)
+ left_list = []
+ right_list = []
+ for i in range(append_num):
+ ly, lx = np.round(left_start + left_step * (i + 1)).flatten().astype(
+ 'int32').tolist()
+ if ly < h and lx < w and (ly, lx) not in left_list:
+ left_list.append((ly, lx))
+ ry, rx = np.round(right_start + right_step * (i + 1)).flatten().astype(
+ 'int32').tolist()
+ if ry < h and rx < w and (ry, rx) not in right_list:
+ right_list.append((ry, rx))
+
+ all_list = left_list[::-1] + sorted_list + right_list
+ return all_list
+
+
+def sort_and_expand_with_direction_v2(pos_list, f_direction, binary_tcl_map):
+ """
+ f_direction: h x w x 2
+ pos_list: [[y, x], [y, x], [y, x] ...]
+ binary_tcl_map: h x w
+ """
+ h, w, _ = f_direction.shape
+ sorted_list, point_direction = sort_with_direction(pos_list, f_direction)
+
+ point_num = len(sorted_list)
+ sub_direction_len = max(point_num // 3, 2)
+ left_direction = point_direction[:sub_direction_len, :]
+ right_dirction = point_direction[point_num - sub_direction_len:, :]
+
+ left_average_direction = -np.mean(left_direction, axis=0, keepdims=True)
+ left_average_len = np.linalg.norm(left_average_direction)
+ left_start = np.array(sorted_list[0])
+ left_step = left_average_direction / (left_average_len + 1e-6)
+
+ right_average_direction = np.mean(right_dirction, axis=0, keepdims=True)
+ right_average_len = np.linalg.norm(right_average_direction)
+ right_step = right_average_direction / (right_average_len + 1e-6)
+ right_start = np.array(sorted_list[-1])
+
+ append_num = max(
+ int((left_average_len + right_average_len) / 2.0 * 0.15), 1)
+ max_append_num = 2 * append_num
+
+ left_list = []
+ right_list = []
+ for i in range(max_append_num):
+ ly, lx = np.round(left_start + left_step * (i + 1)).flatten().astype(
+ 'int32').tolist()
+ if ly < h and lx < w and (ly, lx) not in left_list:
+ if binary_tcl_map[ly, lx] > 0.5:
+ left_list.append((ly, lx))
+ else:
+ break
+
+ for i in range(max_append_num):
+ ry, rx = np.round(right_start + right_step * (i + 1)).flatten().astype(
+ 'int32').tolist()
+ if ry < h and rx < w and (ry, rx) not in right_list:
+ if binary_tcl_map[ry, rx] > 0.5:
+ right_list.append((ry, rx))
+ else:
+ break
+
+ all_list = left_list[::-1] + sorted_list + right_list
+ return all_list
+
+
+def point_pair2poly(point_pair_list):
+ """
+ Transfer vertical point_pairs into poly point in clockwise.
+ """
+ point_num = len(point_pair_list) * 2
+ point_list = [0] * point_num
+ for idx, point_pair in enumerate(point_pair_list):
+ point_list[idx] = point_pair[0]
+ point_list[point_num - 1 - idx] = point_pair[1]
+ return np.array(point_list).reshape(-1, 2)
+
+
+def shrink_quad_along_width(quad, begin_width_ratio=0., end_width_ratio=1.):
+ ratio_pair = np.array(
+ [[begin_width_ratio], [end_width_ratio]], dtype=np.float32)
+ p0_1 = quad[0] + (quad[1] - quad[0]) * ratio_pair
+ p3_2 = quad[3] + (quad[2] - quad[3]) * ratio_pair
+ return np.array([p0_1[0], p0_1[1], p3_2[1], p3_2[0]])
+
+
+def expand_poly_along_width(poly, shrink_ratio_of_width=0.3):
+ """
+ expand poly along width.
+ """
+ point_num = poly.shape[0]
+ left_quad = np.array(
+ [poly[0], poly[1], poly[-2], poly[-1]], dtype=np.float32)
+ left_ratio = -shrink_ratio_of_width * np.linalg.norm(left_quad[0] - left_quad[3]) / \
+ (np.linalg.norm(left_quad[0] - left_quad[1]) + 1e-6)
+ left_quad_expand = shrink_quad_along_width(left_quad, left_ratio, 1.0)
+ right_quad = np.array(
+ [
+ poly[point_num // 2 - 2], poly[point_num // 2 - 1],
+ poly[point_num // 2], poly[point_num // 2 + 1]
+ ],
+ dtype=np.float32)
+ right_ratio = 1.0 + shrink_ratio_of_width * np.linalg.norm(right_quad[0] - right_quad[3]) / \
+ (np.linalg.norm(right_quad[0] - right_quad[1]) + 1e-6)
+ right_quad_expand = shrink_quad_along_width(right_quad, 0.0, right_ratio)
+ poly[0] = left_quad_expand[0]
+ poly[-1] = left_quad_expand[-1]
+ poly[point_num // 2 - 1] = right_quad_expand[1]
+ poly[point_num // 2] = right_quad_expand[2]
+ return poly
+
+
+def restore_poly(instance_yxs_list, seq_strs, p_border, ratio_w, ratio_h, src_w,
+ src_h, valid_set):
+ poly_list = []
+ keep_str_list = []
+ for yx_center_line, keep_str in zip(instance_yxs_list, seq_strs):
+ if len(keep_str) < 2:
+ print('--> too short, {}'.format(keep_str))
+ continue
+
+ offset_expand = 1.0
+ if valid_set == 'totaltext':
+ offset_expand = 1.2
+
+ point_pair_list = []
+ for y, x in yx_center_line:
+ offset = p_border[:, y, x].reshape(2, 2) * offset_expand
+ ori_yx = np.array([y, x], dtype=np.float32)
+ point_pair = (ori_yx + offset)[:, ::-1] * 4.0 / np.array(
+ [ratio_w, ratio_h]).reshape(-1, 2)
+ point_pair_list.append(point_pair)
+
+ detected_poly = point_pair2poly(point_pair_list)
+ detected_poly = expand_poly_along_width(
+ detected_poly, shrink_ratio_of_width=0.2)
+ detected_poly[:, 0] = np.clip(detected_poly[:, 0], a_min=0, a_max=src_w)
+ detected_poly[:, 1] = np.clip(detected_poly[:, 1], a_min=0, a_max=src_h)
+
+ keep_str_list.append(keep_str)
+ if valid_set == 'partvgg':
+ middle_point = len(detected_poly) // 2
+ detected_poly = detected_poly[
+ [0, middle_point - 1, middle_point, -1], :]
+ poly_list.append(detected_poly)
+ elif valid_set == 'totaltext':
+ poly_list.append(detected_poly)
+ else:
+ print('--> Not supported format.')
+ exit(-1)
+ return poly_list, keep_str_list
+
+
+def generate_pivot_list_fast(p_score,
+ p_char_maps,
+ f_direction,
+ Lexicon_Table,
+ score_thresh=0.5,
+ point_gather_mode=None):
+ """
+ return center point and end point of TCL instance; filter with the char maps;
+ """
+ p_score = p_score[0]
+ f_direction = f_direction.transpose(1, 2, 0)
+ p_tcl_map = (p_score > score_thresh) * 1.0
+ skeleton_map = thin(p_tcl_map.astype(np.uint8))
+ instance_count, instance_label_map = cv2.connectedComponents(
+ skeleton_map.astype(np.uint8), connectivity=8)
+
+ # get TCL Instance
+ all_pos_yxs = []
+ if instance_count > 0:
+ for instance_id in range(1, instance_count):
+ pos_list = []
+ ys, xs = np.where(instance_label_map == instance_id)
+ pos_list = list(zip(ys, xs))
+
+ if len(pos_list) < 3:
+ continue
+
+ pos_list_sorted = sort_and_expand_with_direction_v2(
+ pos_list, f_direction, p_tcl_map)
+ all_pos_yxs.append(pos_list_sorted)
+
+ p_char_maps = p_char_maps.transpose([1, 2, 0])
+ decoded_str, keep_yxs_list = ctc_decoder_for_image(
+ all_pos_yxs,
+ logits_map=p_char_maps,
+ Lexicon_Table=Lexicon_Table,
+ point_gather_mode=point_gather_mode)
+ return keep_yxs_list, decoded_str
+
+
+def extract_main_direction(pos_list, f_direction):
+ """
+ f_direction: h x w x 2
+ pos_list: [[y, x], [y, x], [y, x] ...]
+ """
+ pos_list = np.array(pos_list)
+ point_direction = f_direction[pos_list[:, 0], pos_list[:, 1]]
+ point_direction = point_direction[:, ::-1] # x, y -> y, x
+ average_direction = np.mean(point_direction, axis=0, keepdims=True)
+ average_direction = average_direction / (
+ np.linalg.norm(average_direction) + 1e-6)
+ return average_direction
+
+
+def sort_by_direction_with_image_id_deprecated(pos_list, f_direction):
+ """
+ f_direction: h x w x 2
+ pos_list: [[id, y, x], [id, y, x], [id, y, x] ...]
+ """
+ pos_list_full = np.array(pos_list).reshape(-1, 3)
+ pos_list = pos_list_full[:, 1:]
+ point_direction = f_direction[pos_list[:, 0], pos_list[:, 1]] # x, y
+ point_direction = point_direction[:, ::-1] # x, y -> y, x
+ average_direction = np.mean(point_direction, axis=0, keepdims=True)
+ pos_proj_leng = np.sum(pos_list * average_direction, axis=1)
+ sorted_list = pos_list_full[np.argsort(pos_proj_leng)].tolist()
+ return sorted_list
+
+
+def sort_by_direction_with_image_id(pos_list, f_direction):
+ """
+ f_direction: h x w x 2
+ pos_list: [[y, x], [y, x], [y, x] ...]
+ """
+
+ def sort_part_with_direction(pos_list_full, point_direction):
+ pos_list_full = np.array(pos_list_full).reshape(-1, 3)
+ pos_list = pos_list_full[:, 1:]
+ point_direction = np.array(point_direction).reshape(-1, 2)
+ average_direction = np.mean(point_direction, axis=0, keepdims=True)
+ pos_proj_leng = np.sum(pos_list * average_direction, axis=1)
+ sorted_list = pos_list_full[np.argsort(pos_proj_leng)].tolist()
+ sorted_direction = point_direction[np.argsort(pos_proj_leng)].tolist()
+ return sorted_list, sorted_direction
+
+ pos_list = np.array(pos_list).reshape(-1, 3)
+ point_direction = f_direction[pos_list[:, 1], pos_list[:, 2]] # x, y
+ point_direction = point_direction[:, ::-1] # x, y -> y, x
+ sorted_point, sorted_direction = sort_part_with_direction(pos_list,
+ point_direction)
+
+ point_num = len(sorted_point)
+ if point_num >= 16:
+ middle_num = point_num // 2
+ first_part_point = sorted_point[:middle_num]
+ first_point_direction = sorted_direction[:middle_num]
+ sorted_fist_part_point, sorted_fist_part_direction = sort_part_with_direction(
+ first_part_point, first_point_direction)
+
+ last_part_point = sorted_point[middle_num:]
+ last_point_direction = sorted_direction[middle_num:]
+ sorted_last_part_point, sorted_last_part_direction = sort_part_with_direction(
+ last_part_point, last_point_direction)
+ sorted_point = sorted_fist_part_point + sorted_last_part_point
+ sorted_direction = sorted_fist_part_direction + sorted_last_part_direction
+
+ return sorted_point
diff --git a/ocr-studio/PaddleOCR/ppocr/utils/e2e_utils/extract_textpoint_slow.py b/ocr-studio/PaddleOCR/ppocr/utils/e2e_utils/extract_textpoint_slow.py
new file mode 100644
index 0000000000000000000000000000000000000000..ace46fba372e0b6ee27959076e1e855e77c4305c
--- /dev/null
+++ b/ocr-studio/PaddleOCR/ppocr/utils/e2e_utils/extract_textpoint_slow.py
@@ -0,0 +1,592 @@
+# Copyright (c) 2021 PaddlePaddle Authors. All Rights Reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""Contains various CTC decoders."""
+from __future__ import absolute_import
+from __future__ import division
+from __future__ import print_function
+
+import cv2
+import math
+
+import numpy as np
+from itertools import groupby
+from skimage.morphology._skeletonize import thin
+
+
+def get_dict(character_dict_path):
+ character_str = ""
+ with open(character_dict_path, "rb") as fin:
+ lines = fin.readlines()
+ for line in lines:
+ line = line.decode('utf-8').strip("\n").strip("\r\n")
+ character_str += line
+ dict_character = list(character_str)
+ return dict_character
+
+
+def point_pair2poly(point_pair_list):
+ """
+ Transfer vertical point_pairs into poly point in clockwise.
+ """
+ pair_length_list = []
+ for point_pair in point_pair_list:
+ pair_length = np.linalg.norm(point_pair[0] - point_pair[1])
+ pair_length_list.append(pair_length)
+ pair_length_list = np.array(pair_length_list)
+ pair_info = (pair_length_list.max(), pair_length_list.min(),
+ pair_length_list.mean())
+
+ point_num = len(point_pair_list) * 2
+ point_list = [0] * point_num
+ for idx, point_pair in enumerate(point_pair_list):
+ point_list[idx] = point_pair[0]
+ point_list[point_num - 1 - idx] = point_pair[1]
+ return np.array(point_list).reshape(-1, 2), pair_info
+
+
+def shrink_quad_along_width(quad, begin_width_ratio=0., end_width_ratio=1.):
+ """
+ Generate shrink_quad_along_width.
+ """
+ ratio_pair = np.array(
+ [[begin_width_ratio], [end_width_ratio]], dtype=np.float32)
+ p0_1 = quad[0] + (quad[1] - quad[0]) * ratio_pair
+ p3_2 = quad[3] + (quad[2] - quad[3]) * ratio_pair
+ return np.array([p0_1[0], p0_1[1], p3_2[1], p3_2[0]])
+
+
+def expand_poly_along_width(poly, shrink_ratio_of_width=0.3):
+ """
+ expand poly along width.
+ """
+ point_num = poly.shape[0]
+ left_quad = np.array(
+ [poly[0], poly[1], poly[-2], poly[-1]], dtype=np.float32)
+ left_ratio = -shrink_ratio_of_width * np.linalg.norm(left_quad[0] - left_quad[3]) / \
+ (np.linalg.norm(left_quad[0] - left_quad[1]) + 1e-6)
+ left_quad_expand = shrink_quad_along_width(left_quad, left_ratio, 1.0)
+ right_quad = np.array(
+ [
+ poly[point_num // 2 - 2], poly[point_num // 2 - 1],
+ poly[point_num // 2], poly[point_num // 2 + 1]
+ ],
+ dtype=np.float32)
+ right_ratio = 1.0 + \
+ shrink_ratio_of_width * np.linalg.norm(right_quad[0] - right_quad[3]) / \
+ (np.linalg.norm(right_quad[0] - right_quad[1]) + 1e-6)
+ right_quad_expand = shrink_quad_along_width(right_quad, 0.0, right_ratio)
+ poly[0] = left_quad_expand[0]
+ poly[-1] = left_quad_expand[-1]
+ poly[point_num // 2 - 1] = right_quad_expand[1]
+ poly[point_num // 2] = right_quad_expand[2]
+ return poly
+
+
+def softmax(logits):
+ """
+ logits: N x d
+ """
+ max_value = np.max(logits, axis=1, keepdims=True)
+ exp = np.exp(logits - max_value)
+ exp_sum = np.sum(exp, axis=1, keepdims=True)
+ dist = exp / exp_sum
+ return dist
+
+
+def get_keep_pos_idxs(labels, remove_blank=None):
+ """
+ Remove duplicate and get pos idxs of keep items.
+ The value of keep_blank should be [None, 95].
+ """
+ duplicate_len_list = []
+ keep_pos_idx_list = []
+ keep_char_idx_list = []
+ for k, v_ in groupby(labels):
+ current_len = len(list(v_))
+ if k != remove_blank:
+ current_idx = int(sum(duplicate_len_list) + current_len // 2)
+ keep_pos_idx_list.append(current_idx)
+ keep_char_idx_list.append(k)
+ duplicate_len_list.append(current_len)
+ return keep_char_idx_list, keep_pos_idx_list
+
+
+def remove_blank(labels, blank=0):
+ new_labels = [x for x in labels if x != blank]
+ return new_labels
+
+
+def insert_blank(labels, blank=0):
+ new_labels = [blank]
+ for l in labels:
+ new_labels += [l, blank]
+ return new_labels
+
+
+def ctc_greedy_decoder(probs_seq, blank=95, keep_blank_in_idxs=True):
+ """
+ CTC greedy (best path) decoder.
+ """
+ raw_str = np.argmax(np.array(probs_seq), axis=1)
+ remove_blank_in_pos = None if keep_blank_in_idxs else blank
+ dedup_str, keep_idx_list = get_keep_pos_idxs(
+ raw_str, remove_blank=remove_blank_in_pos)
+ dst_str = remove_blank(dedup_str, blank=blank)
+ return dst_str, keep_idx_list
+
+
+def instance_ctc_greedy_decoder(gather_info,
+ logits_map,
+ keep_blank_in_idxs=True):
+ """
+ gather_info: [[x, y], [x, y] ...]
+ logits_map: H x W X (n_chars + 1)
+ """
+ _, _, C = logits_map.shape
+ ys, xs = zip(*gather_info)
+ logits_seq = logits_map[list(ys), list(xs)] # n x 96
+ probs_seq = softmax(logits_seq)
+ dst_str, keep_idx_list = ctc_greedy_decoder(
+ probs_seq, blank=C - 1, keep_blank_in_idxs=keep_blank_in_idxs)
+ keep_gather_list = [gather_info[idx] for idx in keep_idx_list]
+ return dst_str, keep_gather_list
+
+
+def ctc_decoder_for_image(gather_info_list, logits_map,
+ keep_blank_in_idxs=True):
+ """
+ CTC decoder using multiple processes.
+ """
+ decoder_results = []
+ for gather_info in gather_info_list:
+ res = instance_ctc_greedy_decoder(
+ gather_info, logits_map, keep_blank_in_idxs=keep_blank_in_idxs)
+ decoder_results.append(res)
+ return decoder_results
+
+
+def sort_with_direction(pos_list, f_direction):
+ """
+ f_direction: h x w x 2
+ pos_list: [[y, x], [y, x], [y, x] ...]
+ """
+
+ def sort_part_with_direction(pos_list, point_direction):
+ pos_list = np.array(pos_list).reshape(-1, 2)
+ point_direction = np.array(point_direction).reshape(-1, 2)
+ average_direction = np.mean(point_direction, axis=0, keepdims=True)
+ pos_proj_leng = np.sum(pos_list * average_direction, axis=1)
+ sorted_list = pos_list[np.argsort(pos_proj_leng)].tolist()
+ sorted_direction = point_direction[np.argsort(pos_proj_leng)].tolist()
+ return sorted_list, sorted_direction
+
+ pos_list = np.array(pos_list).reshape(-1, 2)
+ point_direction = f_direction[pos_list[:, 0], pos_list[:, 1]] # x, y
+ point_direction = point_direction[:, ::-1] # x, y -> y, x
+ sorted_point, sorted_direction = sort_part_with_direction(pos_list,
+ point_direction)
+
+ point_num = len(sorted_point)
+ if point_num >= 16:
+ middle_num = point_num // 2
+ first_part_point = sorted_point[:middle_num]
+ first_point_direction = sorted_direction[:middle_num]
+ sorted_fist_part_point, sorted_fist_part_direction = sort_part_with_direction(
+ first_part_point, first_point_direction)
+
+ last_part_point = sorted_point[middle_num:]
+ last_point_direction = sorted_direction[middle_num:]
+ sorted_last_part_point, sorted_last_part_direction = sort_part_with_direction(
+ last_part_point, last_point_direction)
+ sorted_point = sorted_fist_part_point + sorted_last_part_point
+ sorted_direction = sorted_fist_part_direction + sorted_last_part_direction
+
+ return sorted_point, np.array(sorted_direction)
+
+
+def add_id(pos_list, image_id=0):
+ """
+ Add id for gather feature, for inference.
+ """
+ new_list = []
+ for item in pos_list:
+ new_list.append((image_id, item[0], item[1]))
+ return new_list
+
+
+def sort_and_expand_with_direction(pos_list, f_direction):
+ """
+ f_direction: h x w x 2
+ pos_list: [[y, x], [y, x], [y, x] ...]
+ """
+ h, w, _ = f_direction.shape
+ sorted_list, point_direction = sort_with_direction(pos_list, f_direction)
+
+ # expand along
+ point_num = len(sorted_list)
+ sub_direction_len = max(point_num // 3, 2)
+ left_direction = point_direction[:sub_direction_len, :]
+ right_dirction = point_direction[point_num - sub_direction_len:, :]
+
+ left_average_direction = -np.mean(left_direction, axis=0, keepdims=True)
+ left_average_len = np.linalg.norm(left_average_direction)
+ left_start = np.array(sorted_list[0])
+ left_step = left_average_direction / (left_average_len + 1e-6)
+
+ right_average_direction = np.mean(right_dirction, axis=0, keepdims=True)
+ right_average_len = np.linalg.norm(right_average_direction)
+ right_step = right_average_direction / (right_average_len + 1e-6)
+ right_start = np.array(sorted_list[-1])
+
+ append_num = max(
+ int((left_average_len + right_average_len) / 2.0 * 0.15), 1)
+ left_list = []
+ right_list = []
+ for i in range(append_num):
+ ly, lx = np.round(left_start + left_step * (i + 1)).flatten().astype(
+ 'int32').tolist()
+ if ly < h and lx < w and (ly, lx) not in left_list:
+ left_list.append((ly, lx))
+ ry, rx = np.round(right_start + right_step * (i + 1)).flatten().astype(
+ 'int32').tolist()
+ if ry < h and rx < w and (ry, rx) not in right_list:
+ right_list.append((ry, rx))
+
+ all_list = left_list[::-1] + sorted_list + right_list
+ return all_list
+
+
+def sort_and_expand_with_direction_v2(pos_list, f_direction, binary_tcl_map):
+ """
+ f_direction: h x w x 2
+ pos_list: [[y, x], [y, x], [y, x] ...]
+ binary_tcl_map: h x w
+ """
+ h, w, _ = f_direction.shape
+ sorted_list, point_direction = sort_with_direction(pos_list, f_direction)
+
+ # expand along
+ point_num = len(sorted_list)
+ sub_direction_len = max(point_num // 3, 2)
+ left_direction = point_direction[:sub_direction_len, :]
+ right_dirction = point_direction[point_num - sub_direction_len:, :]
+
+ left_average_direction = -np.mean(left_direction, axis=0, keepdims=True)
+ left_average_len = np.linalg.norm(left_average_direction)
+ left_start = np.array(sorted_list[0])
+ left_step = left_average_direction / (left_average_len + 1e-6)
+
+ right_average_direction = np.mean(right_dirction, axis=0, keepdims=True)
+ right_average_len = np.linalg.norm(right_average_direction)
+ right_step = right_average_direction / (right_average_len + 1e-6)
+ right_start = np.array(sorted_list[-1])
+
+ append_num = max(
+ int((left_average_len + right_average_len) / 2.0 * 0.15), 1)
+ max_append_num = 2 * append_num
+
+ left_list = []
+ right_list = []
+ for i in range(max_append_num):
+ ly, lx = np.round(left_start + left_step * (i + 1)).flatten().astype(
+ 'int32').tolist()
+ if ly < h and lx < w and (ly, lx) not in left_list:
+ if binary_tcl_map[ly, lx] > 0.5:
+ left_list.append((ly, lx))
+ else:
+ break
+
+ for i in range(max_append_num):
+ ry, rx = np.round(right_start + right_step * (i + 1)).flatten().astype(
+ 'int32').tolist()
+ if ry < h and rx < w and (ry, rx) not in right_list:
+ if binary_tcl_map[ry, rx] > 0.5:
+ right_list.append((ry, rx))
+ else:
+ break
+
+ all_list = left_list[::-1] + sorted_list + right_list
+ return all_list
+
+
+def generate_pivot_list_curved(p_score,
+ p_char_maps,
+ f_direction,
+ score_thresh=0.5,
+ is_expand=True,
+ is_backbone=False,
+ image_id=0):
+ """
+ return center point and end point of TCL instance; filter with the char maps;
+ """
+ p_score = p_score[0]
+ f_direction = f_direction.transpose(1, 2, 0)
+ p_tcl_map = (p_score > score_thresh) * 1.0
+ skeleton_map = thin(p_tcl_map)
+ instance_count, instance_label_map = cv2.connectedComponents(
+ skeleton_map.astype(np.uint8), connectivity=8)
+
+ # get TCL Instance
+ all_pos_yxs = []
+ center_pos_yxs = []
+ end_points_yxs = []
+ instance_center_pos_yxs = []
+ pred_strs = []
+ if instance_count > 0:
+ for instance_id in range(1, instance_count):
+ pos_list = []
+ ys, xs = np.where(instance_label_map == instance_id)
+ pos_list = list(zip(ys, xs))
+
+ ### FIX-ME, eliminate outlier
+ if len(pos_list) < 3:
+ continue
+
+ if is_expand:
+ pos_list_sorted = sort_and_expand_with_direction_v2(
+ pos_list, f_direction, p_tcl_map)
+ else:
+ pos_list_sorted, _ = sort_with_direction(pos_list, f_direction)
+ all_pos_yxs.append(pos_list_sorted)
+
+ # use decoder to filter backgroud points.
+ p_char_maps = p_char_maps.transpose([1, 2, 0])
+ decode_res = ctc_decoder_for_image(
+ all_pos_yxs, logits_map=p_char_maps, keep_blank_in_idxs=True)
+ for decoded_str, keep_yxs_list in decode_res:
+ if is_backbone:
+ keep_yxs_list_with_id = add_id(keep_yxs_list, image_id=image_id)
+ instance_center_pos_yxs.append(keep_yxs_list_with_id)
+ pred_strs.append(decoded_str)
+ else:
+ end_points_yxs.extend((keep_yxs_list[0], keep_yxs_list[-1]))
+ center_pos_yxs.extend(keep_yxs_list)
+
+ if is_backbone:
+ return pred_strs, instance_center_pos_yxs
+ else:
+ return center_pos_yxs, end_points_yxs
+
+
+def generate_pivot_list_horizontal(p_score,
+ p_char_maps,
+ f_direction,
+ score_thresh=0.5,
+ is_backbone=False,
+ image_id=0):
+ """
+ return center point and end point of TCL instance; filter with the char maps;
+ """
+ p_score = p_score[0]
+ f_direction = f_direction.transpose(1, 2, 0)
+ p_tcl_map_bi = (p_score > score_thresh) * 1.0
+ instance_count, instance_label_map = cv2.connectedComponents(
+ p_tcl_map_bi.astype(np.uint8), connectivity=8)
+
+ # get TCL Instance
+ all_pos_yxs = []
+ center_pos_yxs = []
+ end_points_yxs = []
+ instance_center_pos_yxs = []
+
+ if instance_count > 0:
+ for instance_id in range(1, instance_count):
+ pos_list = []
+ ys, xs = np.where(instance_label_map == instance_id)
+ pos_list = list(zip(ys, xs))
+
+ ### FIX-ME, eliminate outlier
+ if len(pos_list) < 5:
+ continue
+
+ # add rule here
+ main_direction = extract_main_direction(pos_list,
+ f_direction) # y x
+ reference_directin = np.array([0, 1]).reshape([-1, 2]) # y x
+ is_h_angle = abs(np.sum(
+ main_direction * reference_directin)) < math.cos(math.pi / 180 *
+ 70)
+
+ point_yxs = np.array(pos_list)
+ max_y, max_x = np.max(point_yxs, axis=0)
+ min_y, min_x = np.min(point_yxs, axis=0)
+ is_h_len = (max_y - min_y) < 1.5 * (max_x - min_x)
+
+ pos_list_final = []
+ if is_h_len:
+ xs = np.unique(xs)
+ for x in xs:
+ ys = instance_label_map[:, x].copy().reshape((-1, ))
+ y = int(np.where(ys == instance_id)[0].mean())
+ pos_list_final.append((y, x))
+ else:
+ ys = np.unique(ys)
+ for y in ys:
+ xs = instance_label_map[y, :].copy().reshape((-1, ))
+ x = int(np.where(xs == instance_id)[0].mean())
+ pos_list_final.append((y, x))
+
+ pos_list_sorted, _ = sort_with_direction(pos_list_final,
+ f_direction)
+ all_pos_yxs.append(pos_list_sorted)
+
+ # use decoder to filter backgroud points.
+ p_char_maps = p_char_maps.transpose([1, 2, 0])
+ decode_res = ctc_decoder_for_image(
+ all_pos_yxs, logits_map=p_char_maps, keep_blank_in_idxs=True)
+ for decoded_str, keep_yxs_list in decode_res:
+ if is_backbone:
+ keep_yxs_list_with_id = add_id(keep_yxs_list, image_id=image_id)
+ instance_center_pos_yxs.append(keep_yxs_list_with_id)
+ else:
+ end_points_yxs.extend((keep_yxs_list[0], keep_yxs_list[-1]))
+ center_pos_yxs.extend(keep_yxs_list)
+
+ if is_backbone:
+ return instance_center_pos_yxs
+ else:
+ return center_pos_yxs, end_points_yxs
+
+
+def generate_pivot_list_slow(p_score,
+ p_char_maps,
+ f_direction,
+ score_thresh=0.5,
+ is_backbone=False,
+ is_curved=True,
+ image_id=0):
+ """
+ Warp all the function together.
+ """
+ if is_curved:
+ return generate_pivot_list_curved(
+ p_score,
+ p_char_maps,
+ f_direction,
+ score_thresh=score_thresh,
+ is_expand=True,
+ is_backbone=is_backbone,
+ image_id=image_id)
+ else:
+ return generate_pivot_list_horizontal(
+ p_score,
+ p_char_maps,
+ f_direction,
+ score_thresh=score_thresh,
+ is_backbone=is_backbone,
+ image_id=image_id)
+
+
+# for refine module
+def extract_main_direction(pos_list, f_direction):
+ """
+ f_direction: h x w x 2
+ pos_list: [[y, x], [y, x], [y, x] ...]
+ """
+ pos_list = np.array(pos_list)
+ point_direction = f_direction[pos_list[:, 0], pos_list[:, 1]]
+ point_direction = point_direction[:, ::-1] # x, y -> y, x
+ average_direction = np.mean(point_direction, axis=0, keepdims=True)
+ average_direction = average_direction / (
+ np.linalg.norm(average_direction) + 1e-6)
+ return average_direction
+
+
+def sort_by_direction_with_image_id_deprecated(pos_list, f_direction):
+ """
+ f_direction: h x w x 2
+ pos_list: [[id, y, x], [id, y, x], [id, y, x] ...]
+ """
+ pos_list_full = np.array(pos_list).reshape(-1, 3)
+ pos_list = pos_list_full[:, 1:]
+ point_direction = f_direction[pos_list[:, 0], pos_list[:, 1]] # x, y
+ point_direction = point_direction[:, ::-1] # x, y -> y, x
+ average_direction = np.mean(point_direction, axis=0, keepdims=True)
+ pos_proj_leng = np.sum(pos_list * average_direction, axis=1)
+ sorted_list = pos_list_full[np.argsort(pos_proj_leng)].tolist()
+ return sorted_list
+
+
+def sort_by_direction_with_image_id(pos_list, f_direction):
+ """
+ f_direction: h x w x 2
+ pos_list: [[y, x], [y, x], [y, x] ...]
+ """
+
+ def sort_part_with_direction(pos_list_full, point_direction):
+ pos_list_full = np.array(pos_list_full).reshape(-1, 3)
+ pos_list = pos_list_full[:, 1:]
+ point_direction = np.array(point_direction).reshape(-1, 2)
+ average_direction = np.mean(point_direction, axis=0, keepdims=True)
+ pos_proj_leng = np.sum(pos_list * average_direction, axis=1)
+ sorted_list = pos_list_full[np.argsort(pos_proj_leng)].tolist()
+ sorted_direction = point_direction[np.argsort(pos_proj_leng)].tolist()
+ return sorted_list, sorted_direction
+
+ pos_list = np.array(pos_list).reshape(-1, 3)
+ point_direction = f_direction[pos_list[:, 1], pos_list[:, 2]] # x, y
+ point_direction = point_direction[:, ::-1] # x, y -> y, x
+ sorted_point, sorted_direction = sort_part_with_direction(pos_list,
+ point_direction)
+
+ point_num = len(sorted_point)
+ if point_num >= 16:
+ middle_num = point_num // 2
+ first_part_point = sorted_point[:middle_num]
+ first_point_direction = sorted_direction[:middle_num]
+ sorted_fist_part_point, sorted_fist_part_direction = sort_part_with_direction(
+ first_part_point, first_point_direction)
+
+ last_part_point = sorted_point[middle_num:]
+ last_point_direction = sorted_direction[middle_num:]
+ sorted_last_part_point, sorted_last_part_direction = sort_part_with_direction(
+ last_part_point, last_point_direction)
+ sorted_point = sorted_fist_part_point + sorted_last_part_point
+ sorted_direction = sorted_fist_part_direction + sorted_last_part_direction
+
+ return sorted_point
+
+
+def generate_pivot_list_tt_inference(p_score,
+ p_char_maps,
+ f_direction,
+ score_thresh=0.5,
+ is_backbone=False,
+ is_curved=True,
+ image_id=0):
+ """
+ return center point and end point of TCL instance; filter with the char maps;
+ """
+ p_score = p_score[0]
+ f_direction = f_direction.transpose(1, 2, 0)
+ p_tcl_map = (p_score > score_thresh) * 1.0
+ skeleton_map = thin(p_tcl_map)
+ instance_count, instance_label_map = cv2.connectedComponents(
+ skeleton_map.astype(np.uint8), connectivity=8)
+
+ # get TCL Instance
+ all_pos_yxs = []
+ if instance_count > 0:
+ for instance_id in range(1, instance_count):
+ pos_list = []
+ ys, xs = np.where(instance_label_map == instance_id)
+ pos_list = list(zip(ys, xs))
+ ### FIX-ME, eliminate outlier
+ if len(pos_list) < 3:
+ continue
+ pos_list_sorted = sort_and_expand_with_direction_v2(
+ pos_list, f_direction, p_tcl_map)
+ pos_list_sorted_with_id = add_id(pos_list_sorted, image_id=image_id)
+ all_pos_yxs.append(pos_list_sorted_with_id)
+ return all_pos_yxs
diff --git a/ocr-studio/PaddleOCR/ppocr/utils/e2e_utils/pgnet_pp_utils.py b/ocr-studio/PaddleOCR/ppocr/utils/e2e_utils/pgnet_pp_utils.py
new file mode 100644
index 0000000000000000000000000000000000000000..06a766b0e714e2792c0b0d3069963de998eb9eb7
--- /dev/null
+++ b/ocr-studio/PaddleOCR/ppocr/utils/e2e_utils/pgnet_pp_utils.py
@@ -0,0 +1,169 @@
+# Copyright (c) 2021 PaddlePaddle Authors. All Rights Reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+from __future__ import absolute_import
+from __future__ import division
+from __future__ import print_function
+import paddle
+import os
+import sys
+
+__dir__ = os.path.dirname(__file__)
+sys.path.append(__dir__)
+sys.path.append(os.path.join(__dir__, '..'))
+from extract_textpoint_slow import *
+from extract_textpoint_fast import generate_pivot_list_fast, restore_poly
+
+
+class PGNet_PostProcess(object):
+ # two different post-process
+ def __init__(self,
+ character_dict_path,
+ valid_set,
+ score_thresh,
+ outs_dict,
+ shape_list,
+ point_gather_mode=None):
+ self.Lexicon_Table = get_dict(character_dict_path)
+ self.valid_set = valid_set
+ self.score_thresh = score_thresh
+ self.outs_dict = outs_dict
+ self.shape_list = shape_list
+ self.point_gather_mode = point_gather_mode
+
+ def pg_postprocess_fast(self):
+ p_score = self.outs_dict['f_score']
+ p_border = self.outs_dict['f_border']
+ p_char = self.outs_dict['f_char']
+ p_direction = self.outs_dict['f_direction']
+ if isinstance(p_score, paddle.Tensor):
+ p_score = p_score[0].numpy()
+ p_border = p_border[0].numpy()
+ p_direction = p_direction[0].numpy()
+ p_char = p_char[0].numpy()
+ else:
+ p_score = p_score[0]
+ p_border = p_border[0]
+ p_direction = p_direction[0]
+ p_char = p_char[0]
+
+ src_h, src_w, ratio_h, ratio_w = self.shape_list[0]
+ instance_yxs_list, seq_strs = generate_pivot_list_fast(
+ p_score,
+ p_char,
+ p_direction,
+ self.Lexicon_Table,
+ score_thresh=self.score_thresh,
+ point_gather_mode=self.point_gather_mode)
+ poly_list, keep_str_list = restore_poly(instance_yxs_list, seq_strs,
+ p_border, ratio_w, ratio_h,
+ src_w, src_h, self.valid_set)
+ data = {
+ 'points': poly_list,
+ 'texts': keep_str_list,
+ }
+ return data
+
+ def pg_postprocess_slow(self):
+ p_score = self.outs_dict['f_score']
+ p_border = self.outs_dict['f_border']
+ p_char = self.outs_dict['f_char']
+ p_direction = self.outs_dict['f_direction']
+ if isinstance(p_score, paddle.Tensor):
+ p_score = p_score[0].numpy()
+ p_border = p_border[0].numpy()
+ p_direction = p_direction[0].numpy()
+ p_char = p_char[0].numpy()
+ else:
+ p_score = p_score[0]
+ p_border = p_border[0]
+ p_direction = p_direction[0]
+ p_char = p_char[0]
+ src_h, src_w, ratio_h, ratio_w = self.shape_list[0]
+ is_curved = self.valid_set == "totaltext"
+ char_seq_idx_set, instance_yxs_list = generate_pivot_list_slow(
+ p_score,
+ p_char,
+ p_direction,
+ score_thresh=self.score_thresh,
+ is_backbone=True,
+ is_curved=is_curved)
+ seq_strs = []
+ for char_idx_set in char_seq_idx_set:
+ pr_str = ''.join([self.Lexicon_Table[pos] for pos in char_idx_set])
+ seq_strs.append(pr_str)
+ poly_list = []
+ keep_str_list = []
+ all_point_list = []
+ all_point_pair_list = []
+ for yx_center_line, keep_str in zip(instance_yxs_list, seq_strs):
+ if len(yx_center_line) == 1:
+ yx_center_line.append(yx_center_line[-1])
+
+ offset_expand = 1.0
+ if self.valid_set == 'totaltext':
+ offset_expand = 1.2
+
+ point_pair_list = []
+ for batch_id, y, x in yx_center_line:
+ offset = p_border[:, y, x].reshape(2, 2)
+ if offset_expand != 1.0:
+ offset_length = np.linalg.norm(
+ offset, axis=1, keepdims=True)
+ expand_length = np.clip(
+ offset_length * (offset_expand - 1),
+ a_min=0.5,
+ a_max=3.0)
+ offset_detal = offset / offset_length * expand_length
+ offset = offset + offset_detal
+ ori_yx = np.array([y, x], dtype=np.float32)
+ point_pair = (ori_yx + offset)[:, ::-1] * 4.0 / np.array(
+ [ratio_w, ratio_h]).reshape(-1, 2)
+ point_pair_list.append(point_pair)
+
+ all_point_list.append([
+ int(round(x * 4.0 / ratio_w)),
+ int(round(y * 4.0 / ratio_h))
+ ])
+ all_point_pair_list.append(point_pair.round().astype(np.int32)
+ .tolist())
+
+ detected_poly, pair_length_info = point_pair2poly(point_pair_list)
+ detected_poly = expand_poly_along_width(
+ detected_poly, shrink_ratio_of_width=0.2)
+ detected_poly[:, 0] = np.clip(
+ detected_poly[:, 0], a_min=0, a_max=src_w)
+ detected_poly[:, 1] = np.clip(
+ detected_poly[:, 1], a_min=0, a_max=src_h)
+
+ if len(keep_str) < 2:
+ continue
+
+ keep_str_list.append(keep_str)
+ detected_poly = np.round(detected_poly).astype('int32')
+ if self.valid_set == 'partvgg':
+ middle_point = len(detected_poly) // 2
+ detected_poly = detected_poly[
+ [0, middle_point - 1, middle_point, -1], :]
+ poly_list.append(detected_poly)
+ elif self.valid_set == 'totaltext':
+ poly_list.append(detected_poly)
+ else:
+ print('--> Not supported format.')
+ exit(-1)
+ data = {
+ 'points': poly_list,
+ 'texts': keep_str_list,
+ }
+ return data
diff --git a/ocr-studio/PaddleOCR/ppocr/utils/e2e_utils/visual.py b/ocr-studio/PaddleOCR/ppocr/utils/e2e_utils/visual.py
new file mode 100644
index 0000000000000000000000000000000000000000..e6e4fd0667dbf4a42dbc0fd9bf26e6fd91be0d82
--- /dev/null
+++ b/ocr-studio/PaddleOCR/ppocr/utils/e2e_utils/visual.py
@@ -0,0 +1,162 @@
+# Copyright (c) 2021 PaddlePaddle Authors. All Rights Reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+import numpy as np
+import cv2
+import time
+
+
+def resize_image(im, max_side_len=512):
+ """
+ resize image to a size multiple of max_stride which is required by the network
+ :param im: the resized image
+ :param max_side_len: limit of max image size to avoid out of memory in gpu
+ :return: the resized image and the resize ratio
+ """
+ h, w, _ = im.shape
+
+ resize_w = w
+ resize_h = h
+
+ if resize_h > resize_w:
+ ratio = float(max_side_len) / resize_h
+ else:
+ ratio = float(max_side_len) / resize_w
+
+ resize_h = int(resize_h * ratio)
+ resize_w = int(resize_w * ratio)
+
+ max_stride = 128
+ resize_h = (resize_h + max_stride - 1) // max_stride * max_stride
+ resize_w = (resize_w + max_stride - 1) // max_stride * max_stride
+ im = cv2.resize(im, (int(resize_w), int(resize_h)))
+ ratio_h = resize_h / float(h)
+ ratio_w = resize_w / float(w)
+
+ return im, (ratio_h, ratio_w)
+
+
+def resize_image_min(im, max_side_len=512):
+ """
+ """
+ h, w, _ = im.shape
+
+ resize_w = w
+ resize_h = h
+
+ if resize_h < resize_w:
+ ratio = float(max_side_len) / resize_h
+ else:
+ ratio = float(max_side_len) / resize_w
+
+ resize_h = int(resize_h * ratio)
+ resize_w = int(resize_w * ratio)
+
+ max_stride = 128
+ resize_h = (resize_h + max_stride - 1) // max_stride * max_stride
+ resize_w = (resize_w + max_stride - 1) // max_stride * max_stride
+ im = cv2.resize(im, (int(resize_w), int(resize_h)))
+ ratio_h = resize_h / float(h)
+ ratio_w = resize_w / float(w)
+ return im, (ratio_h, ratio_w)
+
+
+def resize_image_for_totaltext(im, max_side_len=512):
+ """
+ """
+ h, w, _ = im.shape
+
+ resize_w = w
+ resize_h = h
+ ratio = 1.25
+ if h * ratio > max_side_len:
+ ratio = float(max_side_len) / resize_h
+
+ resize_h = int(resize_h * ratio)
+ resize_w = int(resize_w * ratio)
+
+ max_stride = 128
+ resize_h = (resize_h + max_stride - 1) // max_stride * max_stride
+ resize_w = (resize_w + max_stride - 1) // max_stride * max_stride
+ im = cv2.resize(im, (int(resize_w), int(resize_h)))
+ ratio_h = resize_h / float(h)
+ ratio_w = resize_w / float(w)
+ return im, (ratio_h, ratio_w)
+
+
+def point_pair2poly(point_pair_list):
+ """
+ Transfer vertical point_pairs into poly point in clockwise.
+ """
+ pair_length_list = []
+ for point_pair in point_pair_list:
+ pair_length = np.linalg.norm(point_pair[0] - point_pair[1])
+ pair_length_list.append(pair_length)
+ pair_length_list = np.array(pair_length_list)
+ pair_info = (pair_length_list.max(), pair_length_list.min(),
+ pair_length_list.mean())
+
+ point_num = len(point_pair_list) * 2
+ point_list = [0] * point_num
+ for idx, point_pair in enumerate(point_pair_list):
+ point_list[idx] = point_pair[0]
+ point_list[point_num - 1 - idx] = point_pair[1]
+ return np.array(point_list).reshape(-1, 2), pair_info
+
+
+def shrink_quad_along_width(quad, begin_width_ratio=0., end_width_ratio=1.):
+ """
+ Generate shrink_quad_along_width.
+ """
+ ratio_pair = np.array(
+ [[begin_width_ratio], [end_width_ratio]], dtype=np.float32)
+ p0_1 = quad[0] + (quad[1] - quad[0]) * ratio_pair
+ p3_2 = quad[3] + (quad[2] - quad[3]) * ratio_pair
+ return np.array([p0_1[0], p0_1[1], p3_2[1], p3_2[0]])
+
+
+def expand_poly_along_width(poly, shrink_ratio_of_width=0.3):
+ """
+ expand poly along width.
+ """
+ point_num = poly.shape[0]
+ left_quad = np.array(
+ [poly[0], poly[1], poly[-2], poly[-1]], dtype=np.float32)
+ left_ratio = -shrink_ratio_of_width * np.linalg.norm(left_quad[0] - left_quad[3]) / \
+ (np.linalg.norm(left_quad[0] - left_quad[1]) + 1e-6)
+ left_quad_expand = shrink_quad_along_width(left_quad, left_ratio, 1.0)
+ right_quad = np.array(
+ [
+ poly[point_num // 2 - 2], poly[point_num // 2 - 1],
+ poly[point_num // 2], poly[point_num // 2 + 1]
+ ],
+ dtype=np.float32)
+ right_ratio = 1.0 + \
+ shrink_ratio_of_width * np.linalg.norm(right_quad[0] - right_quad[3]) / \
+ (np.linalg.norm(right_quad[0] - right_quad[1]) + 1e-6)
+ right_quad_expand = shrink_quad_along_width(right_quad, 0.0, right_ratio)
+ poly[0] = left_quad_expand[0]
+ poly[-1] = left_quad_expand[-1]
+ poly[point_num // 2 - 1] = right_quad_expand[1]
+ poly[point_num // 2] = right_quad_expand[2]
+ return poly
+
+
+def norm2(x, axis=None):
+ if axis:
+ return np.sqrt(np.sum(x**2, axis=axis))
+ return np.sqrt(np.sum(x**2))
+
+
+def cos(p1, p2):
+ return (p1 * p2).sum() / (norm2(p1) * norm2(p2))
diff --git a/ocr-studio/PaddleOCR/ppocr/utils/ema.py b/ocr-studio/PaddleOCR/ppocr/utils/ema.py
new file mode 100644
index 0000000000000000000000000000000000000000..2c7220fdd13b6ecf7951079711ec6099feb879dc
--- /dev/null
+++ b/ocr-studio/PaddleOCR/ppocr/utils/ema.py
@@ -0,0 +1,123 @@
+# copyright (c) 2024 PaddlePaddle Authors. All Rights Reserve.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import math
+
+import paddle
+
+
+class ModelEMA:
+ """Exponential Moving Average for model parameters.
+
+ Maintains shadow copies of model parameters and updates them with:
+ ema_param = decay * ema_param + (1 - decay) * cur_param
+
+ Reference: PaddleDetection ppdet/optimizer/ema.py
+
+ Args:
+ model (nn.Layer): The model whose parameters will be averaged.
+ decay (float): EMA decay coefficient. Default: 0.9998.
+ gamma (int): Warmup parameter for threshold/exponential decay.
+ Default: 2000.
+ ema_decay_type (str): Decay schedule type, one of
+ 'threshold' (default), 'exponential', 'normal'.
+ ema_filter_no_grad (bool): If True, parameters with
+ stop_gradient=True (e.g. frozen Teacher in distillation)
+ are excluded from EMA and pass through unchanged.
+ BN running stats are kept even if no-grad. Default: False.
+ """
+
+ def __init__(
+ self,
+ model,
+ decay=0.9998,
+ gamma=2000,
+ ema_decay_type="threshold",
+ ema_filter_no_grad=False,
+ ):
+ self.decay = decay
+ self.gamma = gamma
+ self.ema_decay_type = ema_decay_type
+ self.step = 0
+ self._decay = decay
+
+ # Build black list: frozen params (excluding BN running stats)
+ self.ema_black_list = set()
+ if ema_filter_no_grad:
+ bn_state_names = set()
+ for name, layer in model.named_sublayers():
+ if isinstance(layer, (paddle.nn.BatchNorm2D, paddle.nn.BatchNorm1D)):
+ prefix = name + "." if name else ""
+ bn_state_names.add(prefix + "_mean")
+ bn_state_names.add(prefix + "_variance")
+ for n, p in model.named_parameters():
+ if p.stop_gradient and n not in bn_state_names:
+ self.ema_black_list.add(n)
+
+ # Initialize shadow weights
+ self.state_dict = {}
+ for k, v in model.state_dict().items():
+ if k in self.ema_black_list:
+ self.state_dict[k] = v.clone()
+ else:
+ self.state_dict[k] = paddle.zeros_like(v).astype("float32")
+
+ def _get_decay(self):
+ if self.ema_decay_type == "threshold":
+ return min(self.decay, (1 + self.step) / (10 + self.step))
+ elif self.ema_decay_type == "exponential":
+ return self.decay * (1 - math.exp(-(self.step + 1) / self.gamma))
+ else: # normal
+ return self.decay
+
+ def update(self, model):
+ """Update shadow weights with current model parameters."""
+ decay = self._get_decay()
+ self._decay = decay
+ model_dict = model.state_dict()
+ for k, v in self.state_dict.items():
+ if k not in self.ema_black_list and k in model_dict:
+ v = decay * v + (1 - decay) * model_dict[k].astype("float32")
+ v.stop_gradient = True
+ self.state_dict[k] = v
+ self.step += 1
+
+ def apply(self):
+ """Return bias-corrected EMA state dict for eval/save.
+
+ Does NOT modify internal state.
+ """
+ if self.step == 0:
+ return {k: v.clone() for k, v in self.state_dict.items()}
+ state = {}
+ for k, v in self.state_dict.items():
+ if k in self.ema_black_list:
+ state[k] = v
+ else:
+ if self.ema_decay_type != "exponential":
+ # threshold / normal need bias-correction
+ v = v / (1 - self._decay**self.step)
+ v = v.clone()
+ v.stop_gradient = True
+ state[k] = v
+ return state
+
+ def state_dict_for_save(self):
+ """Return serializable dict for checkpoint."""
+ return {"ema_state": self.state_dict, "step": self.step}
+
+ def set_state_dict(self, d):
+ """Restore from checkpoint."""
+ self.state_dict = d["ema_state"]
+ self.step = d["step"]
diff --git a/ocr-studio/PaddleOCR/ppocr/utils/en_dict.txt b/ocr-studio/PaddleOCR/ppocr/utils/en_dict.txt
new file mode 100644
index 0000000000000000000000000000000000000000..7677d31b9d3f08eef2823c2cf051beeab1f0470b
--- /dev/null
+++ b/ocr-studio/PaddleOCR/ppocr/utils/en_dict.txt
@@ -0,0 +1,95 @@
+0
+1
+2
+3
+4
+5
+6
+7
+8
+9
+:
+;
+<
+=
+>
+?
+@
+A
+B
+C
+D
+E
+F
+G
+H
+I
+J
+K
+L
+M
+N
+O
+P
+Q
+R
+S
+T
+U
+V
+W
+X
+Y
+Z
+[
+\
+]
+^
+_
+`
+a
+b
+c
+d
+e
+f
+g
+h
+i
+j
+k
+l
+m
+n
+o
+p
+q
+r
+s
+t
+u
+v
+w
+x
+y
+z
+{
+|
+}
+~
+!
+"
+#
+$
+%
+&
+'
+(
+)
+*
++
+,
+-
+.
+/
+
diff --git a/ocr-studio/PaddleOCR/ppocr/utils/export_model.py b/ocr-studio/PaddleOCR/ppocr/utils/export_model.py
new file mode 100644
index 0000000000000000000000000000000000000000..c6f825f7bba009edecd39bf15f382bd371a4fa8f
--- /dev/null
+++ b/ocr-studio/PaddleOCR/ppocr/utils/export_model.py
@@ -0,0 +1,547 @@
+# Copyright (c) 2024 PaddlePaddle Authors. All Rights Reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import os
+import yaml
+import json
+import copy
+import shutil
+import paddle
+import paddle.nn as nn
+from paddle.jit import to_static
+
+from collections import OrderedDict
+from packaging import version
+from argparse import ArgumentParser, RawDescriptionHelpFormatter
+from ppocr.modeling.architectures import build_model
+from ppocr.postprocess import build_post_process
+from ppocr.utils.save_load import load_model
+from ppocr.utils.logging import get_logger
+
+
+def represent_dictionary_order(self, dict_data):
+ return self.represent_mapping("tag:yaml.org,2002:map", dict_data.items())
+
+
+def setup_orderdict():
+ yaml.add_representer(OrderedDict, represent_dictionary_order)
+
+
+def dump_infer_config(config, path, logger):
+ setup_orderdict()
+ infer_cfg = OrderedDict()
+ if not os.path.exists(os.path.dirname(path)):
+ os.makedirs(os.path.dirname(path))
+ model_name = None
+ if config["Global"].get("model_name", None):
+ model_name = config["Global"]["model_name"]
+ infer_cfg["Global"] = {"model_name": model_name}
+ if config["Global"].get("uniform_output_enabled", True):
+ arch_config = config["Architecture"]
+ if arch_config["algorithm"] in ["SVTR_LCNet", "SVTR_HGNet"]:
+ common_dynamic_shapes = {
+ "x": [[1, 3, 48, 160], [1, 3, 48, 320], [8, 3, 48, 3200]]
+ }
+ elif arch_config["model_type"] == "det":
+ common_dynamic_shapes = {
+ "x": [[1, 3, 32, 32], [1, 3, 736, 736], [1, 3, 4000, 4000]]
+ }
+ elif arch_config["algorithm"] == "SLANet":
+ if model_name == "SLANet_plus":
+ common_dynamic_shapes = {
+ "x": [[1, 3, 32, 32], [1, 3, 64, 448], [1, 3, 488, 488]]
+ }
+ else:
+ common_dynamic_shapes = {
+ "x": [[1, 3, 32, 32], [1, 3, 64, 448], [8, 3, 488, 488]]
+ }
+ elif arch_config["algorithm"] == "SLANeXt":
+ common_dynamic_shapes = {
+ "x": [[1, 3, 512, 512], [1, 3, 512, 512], [1, 3, 512, 512]]
+ }
+ elif arch_config["algorithm"] == "LaTeXOCR":
+ common_dynamic_shapes = {
+ "x": [[1, 1, 32, 32], [1, 1, 64, 448], [1, 1, 192, 672]]
+ }
+ elif arch_config["algorithm"] == "UniMERNet":
+ common_dynamic_shapes = {
+ "x": [[1, 1, 192, 672], [1, 1, 192, 672], [8, 1, 192, 672]]
+ }
+ elif arch_config["algorithm"] in ["PP-FormulaNet-L", "PP-FormulaNet_plus-L"]:
+ common_dynamic_shapes = {
+ "x": [[1, 1, 768, 768], [1, 1, 768, 768], [8, 1, 768, 768]]
+ }
+ elif arch_config["algorithm"] in [
+ "PP-FormulaNet-S",
+ "PP-FormulaNet_plus-S",
+ "PP-FormulaNet_plus-M",
+ ]:
+ common_dynamic_shapes = {
+ "x": [[1, 1, 384, 384], [1, 1, 384, 384], [8, 1, 384, 384]]
+ }
+ else:
+ common_dynamic_shapes = None
+
+ backend_keys = ["paddle_infer", "tensorrt"]
+ hpi_config = {
+ "backend_configs": {
+ key: {
+ (
+ "dynamic_shapes" if key == "tensorrt" else "trt_dynamic_shapes"
+ ): common_dynamic_shapes
+ }
+ for key in backend_keys
+ }
+ }
+ if common_dynamic_shapes:
+ infer_cfg["Hpi"] = hpi_config
+
+ infer_cfg["PreProcess"] = {"transform_ops": config["Eval"]["dataset"]["transforms"]}
+ postprocess = OrderedDict()
+ for k, v in config["PostProcess"].items():
+ if config["Architecture"].get("algorithm") in [
+ "LaTeXOCR",
+ "UniMERNet",
+ "PP-FormulaNet-L",
+ "PP-FormulaNet-S",
+ "PP-FormulaNet_plus-L",
+ "PP-FormulaNet_plus-M",
+ "PP-FormulaNet_plus-S",
+ ]:
+ if k != "rec_char_dict_path":
+ postprocess[k] = v
+ else:
+ postprocess[k] = v
+
+ if config["Architecture"].get("algorithm") in ["LaTeXOCR"]:
+ tokenizer_file = config["Global"].get("rec_char_dict_path")
+ if tokenizer_file is not None:
+ with open(tokenizer_file, encoding="utf-8") as tokenizer_config_handle:
+ character_dict = json.load(tokenizer_config_handle)
+ postprocess["character_dict"] = character_dict
+ elif config["Architecture"].get("algorithm") in [
+ "UniMERNet",
+ "PP-FormulaNet-L",
+ "PP-FormulaNet-S",
+ "PP-FormulaNet_plus-L",
+ "PP-FormulaNet_plus-M",
+ "PP-FormulaNet_plus-S",
+ ]:
+ tokenizer_file = config["Global"].get("rec_char_dict_path")
+ fast_tokenizer_file = os.path.join(tokenizer_file, "tokenizer.json")
+ tokenizer_config_file = os.path.join(tokenizer_file, "tokenizer_config.json")
+ postprocess["character_dict"] = {}
+ if fast_tokenizer_file is not None:
+ with open(fast_tokenizer_file, encoding="utf-8") as tokenizer_config_handle:
+ character_dict = json.load(tokenizer_config_handle)
+ postprocess["character_dict"]["fast_tokenizer_file"] = character_dict
+ if tokenizer_config_file is not None:
+ with open(
+ tokenizer_config_file, encoding="utf-8"
+ ) as tokenizer_config_handle:
+ character_dict = json.load(tokenizer_config_handle)
+ postprocess["character_dict"]["tokenizer_config_file"] = character_dict
+ else:
+ if config["Global"].get("character_dict_path") is not None:
+ with open(config["Global"]["character_dict_path"], encoding="utf-8") as f:
+ lines = f.readlines()
+ character_dict = [line.strip("\n") for line in lines]
+ postprocess["character_dict"] = character_dict
+
+ infer_cfg["PostProcess"] = postprocess
+
+ with open(path, "w", encoding="utf-8") as f:
+ yaml.dump(infer_cfg, f, default_flow_style=False, allow_unicode=True)
+ logger.info("Export inference config file to {}".format(os.path.join(path)))
+
+
+def dynamic_to_static(model, arch_config, logger, input_shape=None):
+ if arch_config["algorithm"] == "SRN":
+ max_text_length = arch_config["Head"]["max_text_length"]
+ other_shape = [
+ paddle.static.InputSpec(shape=[None, 1, 64, 256], dtype="float32"),
+ [
+ paddle.static.InputSpec(shape=[None, 256, 1], dtype="int64"),
+ paddle.static.InputSpec(
+ shape=[None, max_text_length, 1], dtype="int64"
+ ),
+ paddle.static.InputSpec(
+ shape=[None, 8, max_text_length, max_text_length], dtype="int64"
+ ),
+ paddle.static.InputSpec(
+ shape=[None, 8, max_text_length, max_text_length], dtype="int64"
+ ),
+ ],
+ ]
+ model = to_static(model, input_spec=other_shape)
+ elif arch_config["algorithm"] == "SAR":
+ other_shape = [
+ paddle.static.InputSpec(shape=[None, 3, 48, 160], dtype="float32"),
+ [paddle.static.InputSpec(shape=[None], dtype="float32")],
+ ]
+ model = to_static(model, input_spec=other_shape)
+ elif arch_config["algorithm"] in ["SVTR_LCNet", "SVTR_HGNet"]:
+ other_shape = [
+ paddle.static.InputSpec(shape=[None, 3, 48, -1], dtype="float32"),
+ ]
+ model = to_static(model, input_spec=other_shape)
+ elif arch_config["algorithm"] in ["SVTR", "CPPD"]:
+ other_shape = [
+ paddle.static.InputSpec(shape=[None] + input_shape, dtype="float32"),
+ ]
+ model = to_static(model, input_spec=other_shape)
+ elif arch_config["algorithm"] == "PREN":
+ other_shape = [
+ paddle.static.InputSpec(shape=[None, 3, 64, 256], dtype="float32"),
+ ]
+ model = to_static(model, input_spec=other_shape)
+ elif arch_config["model_type"] == "sr":
+ other_shape = [
+ paddle.static.InputSpec(shape=[None, 3, 16, 64], dtype="float32")
+ ]
+ model = to_static(model, input_spec=other_shape)
+ elif arch_config["algorithm"] == "ViTSTR":
+ other_shape = [
+ paddle.static.InputSpec(shape=[None, 1, 224, 224], dtype="float32"),
+ ]
+ model = to_static(model, input_spec=other_shape)
+ elif arch_config["algorithm"] == "ABINet":
+ if not input_shape:
+ input_shape = [3, 32, 128]
+ other_shape = [
+ paddle.static.InputSpec(shape=[None] + input_shape, dtype="float32"),
+ ]
+ model = to_static(model, input_spec=other_shape)
+ elif arch_config["algorithm"] in ["NRTR", "SPIN", "RFL"]:
+ other_shape = [
+ paddle.static.InputSpec(shape=[None, 1, 32, 100], dtype="float32"),
+ ]
+ model = to_static(model, input_spec=other_shape)
+ elif arch_config["algorithm"] in ["SATRN"]:
+ other_shape = [
+ paddle.static.InputSpec(shape=[None, 3, 32, 100], dtype="float32"),
+ ]
+ model = to_static(model, input_spec=other_shape)
+ elif arch_config["algorithm"] == "VisionLAN":
+ other_shape = [
+ paddle.static.InputSpec(shape=[None, 3, 64, 256], dtype="float32"),
+ ]
+ model = to_static(model, input_spec=other_shape)
+ elif arch_config["algorithm"] == "RobustScanner":
+ max_text_length = arch_config["Head"]["max_text_length"]
+ other_shape = [
+ paddle.static.InputSpec(shape=[None, 3, 48, 160], dtype="float32"),
+ [
+ paddle.static.InputSpec(
+ shape=[
+ None,
+ ],
+ dtype="float32",
+ ),
+ paddle.static.InputSpec(shape=[None, max_text_length], dtype="int64"),
+ ],
+ ]
+ model = to_static(model, input_spec=other_shape)
+ elif arch_config["algorithm"] == "CAN":
+ other_shape = [
+ [
+ paddle.static.InputSpec(shape=[None, 1, None, None], dtype="float32"),
+ paddle.static.InputSpec(shape=[None, 1, None, None], dtype="float32"),
+ paddle.static.InputSpec(
+ shape=[None, arch_config["Head"]["max_text_length"]], dtype="int64"
+ ),
+ ]
+ ]
+ model = to_static(model, input_spec=other_shape)
+ elif arch_config["algorithm"] == "LaTeXOCR":
+ other_shape = [
+ paddle.static.InputSpec(shape=[None, 1, None, None], dtype="float32"),
+ ]
+ model = to_static(model, input_spec=other_shape)
+ elif arch_config["algorithm"] == "UniMERNet":
+ model = paddle.jit.to_static(
+ model,
+ input_spec=[
+ paddle.static.InputSpec(shape=[-1, 1, 192, 672], dtype="float32")
+ ],
+ full_graph=True,
+ )
+ elif arch_config["algorithm"] == "SLANeXt":
+ model = paddle.jit.to_static(
+ model,
+ input_spec=[
+ paddle.static.InputSpec(shape=[-1, 3, 512, 512], dtype="float32")
+ ],
+ full_graph=True,
+ )
+ elif arch_config["algorithm"] in ["PP-FormulaNet-L", "PP-FormulaNet_plus-L"]:
+ model = paddle.jit.to_static(
+ model,
+ input_spec=[
+ paddle.static.InputSpec(shape=[-1, 1, 768, 768], dtype="float32")
+ ],
+ full_graph=True,
+ )
+ elif arch_config["algorithm"] in [
+ "PP-FormulaNet-S",
+ "PP-FormulaNet_plus-S",
+ "PP-FormulaNet_plus-M",
+ ]:
+ model = paddle.jit.to_static(
+ model,
+ input_spec=[
+ paddle.static.InputSpec(shape=[-1, 1, 384, 384], dtype="float32")
+ ],
+ full_graph=True,
+ )
+
+ elif arch_config["algorithm"] in ["LayoutLM", "LayoutLMv2", "LayoutXLM"]:
+ input_spec = [
+ paddle.static.InputSpec(shape=[None, 512], dtype="int64"), # input_ids
+ paddle.static.InputSpec(shape=[None, 512, 4], dtype="int64"), # bbox
+ paddle.static.InputSpec(shape=[None, 512], dtype="int64"), # attention_mask
+ paddle.static.InputSpec(shape=[None, 512], dtype="int64"), # token_type_ids
+ paddle.static.InputSpec(shape=[None, 3, 224, 224], dtype="int64"), # image
+ ]
+ if "Re" in arch_config["Backbone"]["name"]:
+ input_spec.extend(
+ [
+ paddle.static.InputSpec(
+ shape=[None, 512, 3], dtype="int64"
+ ), # entities
+ paddle.static.InputSpec(
+ shape=[None, None, 2], dtype="int64"
+ ), # relations
+ ]
+ )
+ if model.backbone.use_visual_backbone is False:
+ input_spec.pop(4)
+ model = to_static(model, input_spec=[input_spec])
+ else:
+ infer_shape = [3, -1, -1]
+ if arch_config["model_type"] == "rec":
+ infer_shape = [3, 32, -1] # for rec model, H must be 32
+ if (
+ "Transform" in arch_config
+ and arch_config["Transform"] is not None
+ and arch_config["Transform"]["name"] == "TPS"
+ ):
+ logger.info(
+ "When there is tps in the network, variable length input is not supported, and the input size needs to be the same as during training"
+ )
+ infer_shape[-1] = 100
+ elif arch_config["model_type"] == "table":
+ infer_shape = [3, 488, 488]
+ if arch_config["algorithm"] == "TableMaster":
+ infer_shape = [3, 480, 480]
+ if arch_config["algorithm"] == "SLANet":
+ infer_shape = [3, -1, -1]
+ model = to_static(
+ model,
+ input_spec=[
+ paddle.static.InputSpec(shape=[None] + infer_shape, dtype="float32")
+ ],
+ )
+
+ if arch_config["model_type"] != "sr":
+ for layer in model.sublayers():
+ if hasattr(layer, "rep") and not getattr(layer, "is_repped", False):
+ layer.rep()
+ return model
+
+
+def export_single_model(
+ model,
+ arch_config,
+ save_path,
+ logger,
+ yaml_path,
+ config,
+ input_shape=None,
+ quanter=None,
+):
+
+ model = dynamic_to_static(model, arch_config, logger, input_shape)
+
+ if quanter is None:
+ try:
+ import encryption # Attempt to import the encryption module for AIStudio's encryption model
+ except (
+ ModuleNotFoundError
+ ): # Encryption is not needed if the module cannot be imported
+ print("Skipping import of the encryption module")
+ paddle_version = version.parse(paddle.__version__)
+ if config["Global"].get("export_with_pir", True):
+ assert (
+ paddle_version >= version.parse("3.0.0b2")
+ or paddle_version == version.parse("0.0.0")
+ ) and os.environ.get("FLAGS_enable_pir_api", None) not in ["0", "False"]
+ paddle.jit.save(model, save_path)
+ else:
+ if paddle_version >= version.parse(
+ "3.0.0b2"
+ ) or paddle_version == version.parse("0.0.0"):
+ model.forward.rollback()
+ with paddle.pir_utils.OldIrGuard():
+ model = dynamic_to_static(model, arch_config, logger, input_shape)
+ paddle.jit.save(model, save_path)
+ else:
+ paddle.jit.save(model, save_path)
+ else:
+ quanter.save_quantized_model(model, save_path)
+ logger.info("inference model is saved to {}".format(save_path))
+ return
+
+
+def convert_bn(model):
+ for n, m in model.named_children():
+ if isinstance(m, nn.SyncBatchNorm):
+ bn = nn.BatchNorm2D(
+ m._num_features, m._momentum, m._epsilon, m._weight_attr, m._bias_attr
+ )
+ bn.set_dict(m.state_dict())
+ setattr(model, n, bn)
+ else:
+ convert_bn(m)
+
+
+def export(config, base_model=None, save_path=None):
+ if paddle.distributed.get_rank() != 0:
+ return
+ logger = get_logger()
+ # build post process
+ post_process_class = build_post_process(config["PostProcess"], config["Global"])
+
+ # build model
+ # for rec algorithm
+ if hasattr(post_process_class, "character"):
+ char_num = len(getattr(post_process_class, "character"))
+ if config["Architecture"]["algorithm"] in [
+ "Distillation",
+ ]: # distillation model
+ for key in config["Architecture"]["Models"]:
+ if (
+ config["Architecture"]["Models"][key]["Head"]["name"] == "MultiHead"
+ ): # multi head
+ out_channels_list = {}
+ if config["PostProcess"]["name"] == "DistillationSARLabelDecode":
+ char_num = char_num - 2
+ if config["PostProcess"]["name"] == "DistillationNRTRLabelDecode":
+ char_num = char_num - 3
+ out_channels_list["CTCLabelDecode"] = char_num
+ out_channels_list["SARLabelDecode"] = char_num + 2
+ out_channels_list["NRTRLabelDecode"] = char_num + 3
+ config["Architecture"]["Models"][key]["Head"][
+ "out_channels_list"
+ ] = out_channels_list
+ else:
+ config["Architecture"]["Models"][key]["Head"][
+ "out_channels"
+ ] = char_num
+ # just one final tensor needs to exported for inference
+ config["Architecture"]["Models"][key]["return_all_feats"] = False
+ elif config["Architecture"]["Head"]["name"] == "MultiHead": # multi head
+ out_channels_list = {}
+ char_num = len(getattr(post_process_class, "character"))
+ if config["PostProcess"]["name"] == "SARLabelDecode":
+ char_num = char_num - 2
+ if config["PostProcess"]["name"] == "NRTRLabelDecode":
+ char_num = char_num - 3
+ out_channels_list["CTCLabelDecode"] = char_num
+ out_channels_list["SARLabelDecode"] = char_num + 2
+ out_channels_list["NRTRLabelDecode"] = char_num + 3
+ config["Architecture"]["Head"]["out_channels_list"] = out_channels_list
+ else: # base rec model
+ config["Architecture"]["Head"]["out_channels"] = char_num
+
+ # for sr algorithm
+ if config["Architecture"]["model_type"] == "sr":
+ config["Architecture"]["Transform"]["infer_mode"] = True
+
+ # for latexocr algorithm
+ if config["Architecture"].get("algorithm") in ["LaTeXOCR"]:
+ config["Architecture"]["Backbone"]["is_predict"] = True
+ config["Architecture"]["Backbone"]["is_export"] = True
+ config["Architecture"]["Head"]["is_export"] = True
+ if config["Architecture"].get("algorithm") in ["UniMERNet"]:
+ config["Architecture"]["Backbone"]["is_export"] = True
+ config["Architecture"]["Head"]["is_export"] = True
+ if config["Architecture"].get("algorithm") in [
+ "PP-FormulaNet-S",
+ "PP-FormulaNet-L",
+ "PP-FormulaNet_plus-S",
+ "PP-FormulaNet_plus-M",
+ "PP-FormulaNet_plus-L",
+ ]:
+ config["Architecture"]["Head"]["is_export"] = True
+ if base_model is not None:
+ model = base_model
+ if isinstance(model, paddle.DataParallel):
+ model = copy.deepcopy(model._layers)
+ else:
+ model = copy.deepcopy(model)
+ else:
+ model = build_model(config["Architecture"])
+ load_model(config, model, model_type=config["Architecture"]["model_type"])
+ convert_bn(model)
+ model.eval()
+
+ if not save_path:
+ save_path = config["Global"]["save_inference_dir"]
+ yaml_path = os.path.join(save_path, "inference.yml")
+
+ arch_config = config["Architecture"]
+
+ if (
+ arch_config["algorithm"] in ["SVTR", "CPPD"]
+ and arch_config["Head"]["name"] != "MultiHead"
+ ):
+ input_shape = config["Eval"]["dataset"]["transforms"][-2]["SVTRRecResizeImg"][
+ "image_shape"
+ ]
+ elif arch_config["algorithm"].lower() == "ABINet".lower():
+ rec_rs = [
+ c
+ for c in config["Eval"]["dataset"]["transforms"]
+ if "ABINetRecResizeImg" in c
+ ]
+ input_shape = rec_rs[0]["ABINetRecResizeImg"]["image_shape"] if rec_rs else None
+ else:
+ input_shape = None
+ dump_infer_config(config, yaml_path, logger)
+ if arch_config["algorithm"] in [
+ "Distillation",
+ ]: # distillation model
+ archs = list(arch_config["Models"].values())
+ for idx, name in enumerate(model.model_name_list):
+ sub_model_save_path = os.path.join(save_path, name, "inference")
+ export_single_model(
+ model.model_list[idx],
+ archs[idx],
+ sub_model_save_path,
+ logger,
+ yaml_path,
+ config,
+ )
+ else:
+ save_path = os.path.join(save_path, "inference")
+ export_single_model(
+ model,
+ arch_config,
+ save_path,
+ logger,
+ yaml_path,
+ config,
+ input_shape=input_shape,
+ )
diff --git a/ocr-studio/PaddleOCR/ppocr/utils/formula_utils/math_txt2pkl.py b/ocr-studio/PaddleOCR/ppocr/utils/formula_utils/math_txt2pkl.py
new file mode 100644
index 0000000000000000000000000000000000000000..eb7023fb4cce627a8018538d8858a959b2173b3b
--- /dev/null
+++ b/ocr-studio/PaddleOCR/ppocr/utils/formula_utils/math_txt2pkl.py
@@ -0,0 +1,74 @@
+# copyright (c) 2024 PaddlePaddle Authors. All Rights Reserve.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import pickle
+from tqdm import tqdm
+import os
+import math
+from paddle.utils import try_import
+from collections import defaultdict
+import glob
+from os.path import join
+import argparse
+
+
+def txt2pickle(images, equations, save_dir):
+ imagesize = try_import("imagesize")
+ save_p = os.path.join(save_dir, "latexocr_{}.pkl".format(images.split("/")[-1]))
+ min_dimensions = (32, 32)
+ max_dimensions = (672, 192)
+ max_length = 512
+ data = defaultdict(lambda: [])
+ if images is not None and equations is not None:
+ images_list = [
+ path.replace("\\", "/") for path in glob.glob(join(images, "*.png"))
+ ]
+ indices = [int(os.path.basename(img).split(".")[0]) for img in images_list]
+ eqs = open(equations, "r").read().split("\n")
+ for i, im in tqdm(enumerate(images_list), total=len(images_list)):
+ width, height = imagesize.get(im)
+ if (
+ min_dimensions[0] <= width <= max_dimensions[0]
+ and min_dimensions[1] <= height <= max_dimensions[1]
+ ):
+ divide_h = math.ceil(height / 16) * 16
+ divide_w = math.ceil(width / 16) * 16
+ im = os.path.basename(im)
+ data[(divide_w, divide_h)].append((eqs[indices[i]], im))
+ data = dict(data)
+ with open(save_p, "wb") as file:
+ pickle.dump(data, file)
+
+
+if __name__ == "__main__":
+ parser = argparse.ArgumentParser()
+
+ parser.add_argument(
+ "--image_dir",
+ type=str,
+ default=".",
+ help="Input_label or input path to be converted",
+ )
+ parser.add_argument(
+ "--mathtxt_path",
+ type=str,
+ default=".",
+ help="Input_label or input path to be converted",
+ )
+ parser.add_argument(
+ "--output_dir", type=str, default="out_label.txt", help="Output file name"
+ )
+
+ args = parser.parse_args()
+ txt2pickle(args.image_dir, args.mathtxt_path, args.output_dir)
diff --git a/ocr-studio/PaddleOCR/ppocr/utils/formula_utils/unimernet_data_convert.py b/ocr-studio/PaddleOCR/ppocr/utils/formula_utils/unimernet_data_convert.py
new file mode 100644
index 0000000000000000000000000000000000000000..0cb887ff52c68fd3860227c97b0e48258ded1719
--- /dev/null
+++ b/ocr-studio/PaddleOCR/ppocr/utils/formula_utils/unimernet_data_convert.py
@@ -0,0 +1,107 @@
+# copyright (c) 2024 PaddlePaddle Authors. All Rights Reserve.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import os
+import cv2
+import glob
+import argparse
+from os.path import join
+from tqdm import tqdm
+
+
+def latexocr2paddleocr_train(image_path, math_unimernet_file, math_hwe_file, save_path):
+ convert_f = open(save_path, "w")
+ sub_dir = "UniMER-1M/images"
+ img_sub_dir = os.path.join(image_path, sub_dir)
+ with open(math_unimernet_file, "r") as f:
+ lines = f.readlines()
+ formula_num = len(lines)
+ for i, line in tqdm(enumerate(lines), total=formula_num):
+ image_name = "{0:07d}.png".format(i)
+ math_gt = line.strip()
+ image_p = os.path.join(img_sub_dir, image_name)
+ img_name_subdir = os.path.join(sub_dir, image_name)
+ if os.path.exists(image_p):
+ convert_f.writelines("{}\t{}\n".format(img_name_subdir, math_gt))
+
+ sub_dir = "HME100K/train_images"
+ img_sub_dir = os.path.join(image_path, sub_dir)
+ with open(math_hwe_file, "r") as f:
+ lines = f.readlines()
+ formula_num = len(lines)
+ for i, line in tqdm(enumerate(lines), total=formula_num):
+ img_name, math_gt = line.strip().split("\t")
+ image_path = os.path.join(img_sub_dir, img_name)
+ img_name_subdir = os.path.join(sub_dir, img_name)
+ convert_f.writelines("{}\t{}\n".format(img_name_subdir, math_gt))
+
+ convert_f.close()
+
+
+def unimernet2paddleocr_test(image_path, math_file, save_path):
+ convert_f = open(save_path, "w")
+ with open(math_file, "r") as f:
+ # load maths which
+ lines = f.readlines()
+ formula_num = len(lines)
+ for i, line in tqdm(enumerate(lines), total=formula_num):
+ image_name = "{0:07d}.png".format(i)
+ math_gt = line.strip()
+ image_p = os.path.join(image_path, image_name)
+ if os.path.exists(image_p):
+ convert_f.writelines("{}\t{}\n".format(image_name, math_gt))
+ convert_f.close()
+
+
+if __name__ == "__main__":
+ parser = argparse.ArgumentParser()
+
+ parser.add_argument(
+ "--image_dir",
+ type=str,
+ default=".",
+ help="Input_label or input path to be converted",
+ )
+ parser.add_argument(
+ "--unimernet_txt_path",
+ type=str,
+ default="",
+ help="Input_label or input path to be converted",
+ )
+ parser.add_argument(
+ "--hme100k_txt_path",
+ type=str,
+ default="",
+ help="Input_label or input path to be converted",
+ )
+ parser.add_argument(
+ "--output_path", type=str, default="out_label.txt", help="Output file name"
+ )
+ parser.add_argument(
+ "--datatype", type=str, default="out_label.txt", help="datatype"
+ )
+ args = parser.parse_args()
+ if args.datatype == "unimernet_train":
+ latexocr2paddleocr_train(
+ args.image_dir,
+ args.unimernet_txt_path,
+ args.hme100k_txt_path,
+ args.output_path,
+ )
+ elif args.datatype == "unimernet_test":
+ unimernet2paddleocr_test(
+ args.image_dir, args.unimernet_txt_path, args.output_path
+ )
+ else:
+ raise NotImplementedError("the datatype is not supported")
diff --git a/ocr-studio/PaddleOCR/ppocr/utils/gen_label.py b/ocr-studio/PaddleOCR/ppocr/utils/gen_label.py
new file mode 100644
index 0000000000000000000000000000000000000000..56d75544dbee596a87343c90320b0ea3178e6b28
--- /dev/null
+++ b/ocr-studio/PaddleOCR/ppocr/utils/gen_label.py
@@ -0,0 +1,81 @@
+# copyright (c) 2020 PaddlePaddle Authors. All Rights Reserve.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+import os
+import argparse
+import json
+
+
+def gen_rec_label(input_path, out_label):
+ with open(out_label, 'w') as out_file:
+ with open(input_path, 'r') as f:
+ for line in f.readlines():
+ tmp = line.strip('\n').replace(" ", "").split(',')
+ img_path, label = tmp[0], tmp[1]
+ label = label.replace("\"", "")
+ out_file.write(img_path + '\t' + label + '\n')
+
+
+def gen_det_label(root_path, input_dir, out_label):
+ with open(out_label, 'w') as out_file:
+ for label_file in os.listdir(input_dir):
+ img_path = os.path.join(root_path, label_file[3:-4] + ".jpg")
+ label = []
+ with open(
+ os.path.join(input_dir, label_file), 'r',
+ encoding='utf-8-sig') as f:
+ for line in f.readlines():
+ tmp = line.strip("\n\r").replace("\xef\xbb\xbf",
+ "").split(',')
+ points = tmp[:8]
+ s = []
+ for i in range(0, len(points), 2):
+ b = points[i:i + 2]
+ b = [int(t) for t in b]
+ s.append(b)
+ result = {"transcription": tmp[8], "points": s}
+ label.append(result)
+
+ out_file.write(img_path + '\t' + json.dumps(
+ label, ensure_ascii=False) + '\n')
+
+
+if __name__ == "__main__":
+ parser = argparse.ArgumentParser()
+ parser.add_argument(
+ '--mode',
+ type=str,
+ default="rec",
+ help='Generate rec_label or det_label, can be set rec or det')
+ parser.add_argument(
+ '--root_path',
+ type=str,
+ default=".",
+ help='The root directory of images.Only takes effect when mode=det ')
+ parser.add_argument(
+ '--input_path',
+ type=str,
+ default=".",
+ help='Input_label or input path to be converted')
+ parser.add_argument(
+ '--output_label',
+ type=str,
+ default="out_label.txt",
+ help='Output file name')
+
+ args = parser.parse_args()
+ if args.mode == "rec":
+ print("Generate rec label")
+ gen_rec_label(args.input_path, args.output_label)
+ elif args.mode == "det":
+ gen_det_label(args.root_path, args.input_path, args.output_label)
diff --git a/ocr-studio/PaddleOCR/ppocr/utils/ic15_dict.txt b/ocr-studio/PaddleOCR/ppocr/utils/ic15_dict.txt
new file mode 100644
index 0000000000000000000000000000000000000000..474060366f8a2a00c108d5c743821c0a61867cd5
--- /dev/null
+++ b/ocr-studio/PaddleOCR/ppocr/utils/ic15_dict.txt
@@ -0,0 +1,36 @@
+0
+1
+2
+3
+4
+5
+6
+7
+8
+9
+a
+b
+c
+d
+e
+f
+g
+h
+i
+j
+k
+l
+m
+n
+o
+p
+q
+r
+s
+t
+u
+v
+w
+x
+y
+z
\ No newline at end of file
diff --git a/ocr-studio/PaddleOCR/ppocr/utils/iou.py b/ocr-studio/PaddleOCR/ppocr/utils/iou.py
new file mode 100644
index 0000000000000000000000000000000000000000..35459f5f053cde0a74f76c5652bfb723a48ca890
--- /dev/null
+++ b/ocr-studio/PaddleOCR/ppocr/utils/iou.py
@@ -0,0 +1,54 @@
+# copyright (c) 2021 PaddlePaddle Authors. All Rights Reserve.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+This code is refer from:
+https://github.com/whai362/PSENet/blob/python3/models/loss/iou.py
+"""
+
+import paddle
+
+EPS = 1e-6
+
+
+def iou_single(a, b, mask, n_class):
+ valid = mask == 1
+ a = a.masked_select(valid)
+ b = b.masked_select(valid)
+ miou = []
+ for i in range(n_class):
+ if a.shape == [0] and a.shape == b.shape:
+ inter = paddle.to_tensor(0.0)
+ union = paddle.to_tensor(0.0)
+ else:
+ inter = ((a == i).logical_and(b == i)).astype('float32')
+ union = ((a == i).logical_or(b == i)).astype('float32')
+ miou.append(paddle.sum(inter) / (paddle.sum(union) + EPS))
+ miou = sum(miou) / len(miou)
+ return miou
+
+
+def iou(a, b, mask, n_class=2, reduce=True):
+ batch_size = a.shape[0]
+
+ a = a.reshape([batch_size, -1])
+ b = b.reshape([batch_size, -1])
+ mask = mask.reshape([batch_size, -1])
+
+ iou = paddle.zeros((batch_size, ), dtype='float32')
+ for i in range(batch_size):
+ iou[i] = iou_single(a[i], b[i], mask[i], n_class)
+
+ if reduce:
+ iou = paddle.mean(iou)
+ return iou
diff --git a/ocr-studio/PaddleOCR/ppocr/utils/loggers/__init__.py b/ocr-studio/PaddleOCR/ppocr/utils/loggers/__init__.py
new file mode 100644
index 0000000000000000000000000000000000000000..b1e92f734e84b7e0278f8e7940ef3baf137c159e
--- /dev/null
+++ b/ocr-studio/PaddleOCR/ppocr/utils/loggers/__init__.py
@@ -0,0 +1,3 @@
+from .vdl_logger import VDLLogger
+from .wandb_logger import WandbLogger
+from .loggers import Loggers
diff --git a/ocr-studio/PaddleOCR/ppocr/utils/loggers/base_logger.py b/ocr-studio/PaddleOCR/ppocr/utils/loggers/base_logger.py
new file mode 100644
index 0000000000000000000000000000000000000000..3a7fc3593ba8e69fdd5bed386c7ae4ff0d459988
--- /dev/null
+++ b/ocr-studio/PaddleOCR/ppocr/utils/loggers/base_logger.py
@@ -0,0 +1,15 @@
+import os
+from abc import ABC, abstractmethod
+
+class BaseLogger(ABC):
+ def __init__(self, save_dir):
+ self.save_dir = save_dir
+ os.makedirs(self.save_dir, exist_ok=True)
+
+ @abstractmethod
+ def log_metrics(self, metrics, prefix=None):
+ pass
+
+ @abstractmethod
+ def close(self):
+ pass
\ No newline at end of file
diff --git a/ocr-studio/PaddleOCR/ppocr/utils/loggers/loggers.py b/ocr-studio/PaddleOCR/ppocr/utils/loggers/loggers.py
new file mode 100644
index 0000000000000000000000000000000000000000..260146620811c8e72da66e9f2c7bbcbaef90b90d
--- /dev/null
+++ b/ocr-studio/PaddleOCR/ppocr/utils/loggers/loggers.py
@@ -0,0 +1,18 @@
+from .wandb_logger import WandbLogger
+
+class Loggers(object):
+ def __init__(self, loggers):
+ super().__init__()
+ self.loggers = loggers
+
+ def log_metrics(self, metrics, prefix=None, step=None):
+ for logger in self.loggers:
+ logger.log_metrics(metrics, prefix=prefix, step=step)
+
+ def log_model(self, is_best, prefix, metadata=None):
+ for logger in self.loggers:
+ logger.log_model(is_best=is_best, prefix=prefix, metadata=metadata)
+
+ def close(self):
+ for logger in self.loggers:
+ logger.close()
\ No newline at end of file
diff --git a/ocr-studio/PaddleOCR/ppocr/utils/loggers/vdl_logger.py b/ocr-studio/PaddleOCR/ppocr/utils/loggers/vdl_logger.py
new file mode 100644
index 0000000000000000000000000000000000000000..c345f93235b239873f0ddcd49c8b1b8966877a03
--- /dev/null
+++ b/ocr-studio/PaddleOCR/ppocr/utils/loggers/vdl_logger.py
@@ -0,0 +1,21 @@
+from .base_logger import BaseLogger
+from visualdl import LogWriter
+
+class VDLLogger(BaseLogger):
+ def __init__(self, save_dir):
+ super().__init__(save_dir)
+ self.vdl_writer = LogWriter(logdir=save_dir)
+
+ def log_metrics(self, metrics, prefix=None, step=None):
+ if not prefix:
+ prefix = ""
+ updated_metrics = {prefix + "/" + k: v for k, v in metrics.items()}
+
+ for k, v in updated_metrics.items():
+ self.vdl_writer.add_scalar(k, v, step)
+
+ def log_model(self, is_best, prefix, metadata=None):
+ pass
+
+ def close(self):
+ self.vdl_writer.close()
\ No newline at end of file
diff --git a/ocr-studio/PaddleOCR/ppocr/utils/loggers/wandb_logger.py b/ocr-studio/PaddleOCR/ppocr/utils/loggers/wandb_logger.py
new file mode 100644
index 0000000000000000000000000000000000000000..b9c6711696569e825638e0a27394071020b29cb5
--- /dev/null
+++ b/ocr-studio/PaddleOCR/ppocr/utils/loggers/wandb_logger.py
@@ -0,0 +1,78 @@
+import os
+from .base_logger import BaseLogger
+
+class WandbLogger(BaseLogger):
+ def __init__(self,
+ project=None,
+ name=None,
+ id=None,
+ entity=None,
+ save_dir=None,
+ config=None,
+ **kwargs):
+ try:
+ import wandb
+ self.wandb = wandb
+ except ModuleNotFoundError:
+ raise ModuleNotFoundError(
+ "Please install wandb using `pip install wandb`"
+ )
+
+ self.project = project
+ self.name = name
+ self.id = id
+ self.save_dir = save_dir
+ self.config = config
+ self.kwargs = kwargs
+ self.entity = entity
+ self._run = None
+ self._wandb_init = dict(
+ project=self.project,
+ name=self.name,
+ id=self.id,
+ entity=self.entity,
+ dir=self.save_dir,
+ resume="allow"
+ )
+ self._wandb_init.update(**kwargs)
+
+ _ = self.run
+
+ if self.config:
+ self.run.config.update(self.config)
+
+ @property
+ def run(self):
+ if self._run is None:
+ if self.wandb.run is not None:
+ logger.info(
+ "There is a wandb run already in progress "
+ "and newly created instances of `WandbLogger` will reuse"
+ " this run. If this is not desired, call `wandb.finish()`"
+ "before instantiating `WandbLogger`."
+ )
+ self._run = self.wandb.run
+ else:
+ self._run = self.wandb.init(**self._wandb_init)
+ return self._run
+
+ def log_metrics(self, metrics, prefix=None, step=None):
+ if not prefix:
+ prefix = ""
+ updated_metrics = {prefix.lower() + "/" + k: v for k, v in metrics.items()}
+
+ self.run.log(updated_metrics, step=step)
+
+ def log_model(self, is_best, prefix, metadata=None):
+ model_path = os.path.join(self.save_dir, prefix + '.pdparams')
+ artifact = self.wandb.Artifact('model-{}'.format(self.run.id), type='model', metadata=metadata)
+ artifact.add_file(model_path, name="model_ckpt.pdparams")
+
+ aliases = [prefix]
+ if is_best:
+ aliases.append("best")
+
+ self.run.log_artifact(artifact, aliases=aliases)
+
+ def close(self):
+ self.run.finish()
\ No newline at end of file
diff --git a/ocr-studio/PaddleOCR/ppocr/utils/logging.py b/ocr-studio/PaddleOCR/ppocr/utils/logging.py
new file mode 100644
index 0000000000000000000000000000000000000000..1eac8f351a4d30915d6f4ca863267cb73b9b1f19
--- /dev/null
+++ b/ocr-studio/PaddleOCR/ppocr/utils/logging.py
@@ -0,0 +1,71 @@
+# copyright (c) 2020 PaddlePaddle Authors. All Rights Reserve.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+"""
+This code is refer from:
+https://github.com/WenmuZhou/PytorchOCR/blob/master/torchocr/utils/logging.py
+"""
+
+import os
+import sys
+import logging
+import functools
+import paddle.distributed as dist
+
+logger_initialized = {}
+
+
+@functools.lru_cache()
+def get_logger(name='ppocr', log_file=None, log_level=logging.DEBUG):
+ """Initialize and get a logger by name.
+ If the logger has not been initialized, this method will initialize the
+ logger by adding one or two handlers, otherwise the initialized logger will
+ be directly returned. During initialization, a StreamHandler will always be
+ added. If `log_file` is specified a FileHandler will also be added.
+ Args:
+ name (str): Logger name.
+ log_file (str | None): The log filename. If specified, a FileHandler
+ will be added to the logger.
+ log_level (int): The logger level. Note that only the process of
+ rank 0 is affected, and other processes will set the level to
+ "Error" thus be silent most of the time.
+ Returns:
+ logging.Logger: The expected logger.
+ """
+ logger = logging.getLogger(name)
+ if name in logger_initialized:
+ return logger
+ for logger_name in logger_initialized:
+ if name.startswith(logger_name):
+ return logger
+
+ formatter = logging.Formatter(
+ '[%(asctime)s] %(name)s %(levelname)s: %(message)s',
+ datefmt="%Y/%m/%d %H:%M:%S")
+
+ stream_handler = logging.StreamHandler(stream=sys.stdout)
+ stream_handler.setFormatter(formatter)
+ logger.addHandler(stream_handler)
+ if log_file is not None and dist.get_rank() == 0:
+ log_file_folder = os.path.split(log_file)[0]
+ os.makedirs(log_file_folder, exist_ok=True)
+ file_handler = logging.FileHandler(log_file, 'a')
+ file_handler.setFormatter(formatter)
+ logger.addHandler(file_handler)
+ if dist.get_rank() == 0:
+ logger.setLevel(log_level)
+ else:
+ logger.setLevel(logging.ERROR)
+ logger_initialized[name] = True
+ logger.propagate = False
+ return logger
diff --git a/ocr-studio/PaddleOCR/ppocr/utils/network.py b/ocr-studio/PaddleOCR/ppocr/utils/network.py
new file mode 100644
index 0000000000000000000000000000000000000000..f2cd690e12fd06f2749320f1319fde9de8ebe18d
--- /dev/null
+++ b/ocr-studio/PaddleOCR/ppocr/utils/network.py
@@ -0,0 +1,96 @@
+# copyright (c) 2020 PaddlePaddle Authors. All Rights Reserve.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import os
+import sys
+import tarfile
+import requests
+from tqdm import tqdm
+
+from ppocr.utils.logging import get_logger
+
+MODELS_DIR = os.path.expanduser("~/.paddleocr/models/")
+
+
+def download_with_progressbar(url, save_path):
+ logger = get_logger()
+ response = requests.get(url, stream=True)
+ if response.status_code == 200:
+ total_size_in_bytes = int(response.headers.get('content-length', 1))
+ block_size = 1024 # 1 Kibibyte
+ progress_bar = tqdm(
+ total=total_size_in_bytes, unit='iB', unit_scale=True)
+ with open(save_path, 'wb') as file:
+ for data in response.iter_content(block_size):
+ progress_bar.update(len(data))
+ file.write(data)
+ progress_bar.close()
+ else:
+ logger.error("Something went wrong while downloading models")
+ sys.exit(0)
+
+
+def maybe_download(model_storage_directory, url):
+ # using custom model
+ tar_file_name_list = ['.pdiparams', '.pdiparams.info', '.pdmodel']
+ if not os.path.exists(
+ os.path.join(model_storage_directory, 'inference.pdiparams')
+ ) or not os.path.exists(
+ os.path.join(model_storage_directory, 'inference.pdmodel')):
+ assert url.endswith('.tar'), 'Only supports tar compressed package'
+ tmp_path = os.path.join(model_storage_directory, url.split('/')[-1])
+ print('download {} to {}'.format(url, tmp_path))
+ os.makedirs(model_storage_directory, exist_ok=True)
+ download_with_progressbar(url, tmp_path)
+ with tarfile.open(tmp_path, 'r') as tarObj:
+ for member in tarObj.getmembers():
+ filename = None
+ for tar_file_name in tar_file_name_list:
+ if member.name.endswith(tar_file_name):
+ filename = 'inference' + tar_file_name
+ if filename is None:
+ continue
+ file = tarObj.extractfile(member)
+ with open(
+ os.path.join(model_storage_directory, filename),
+ 'wb') as f:
+ f.write(file.read())
+ os.remove(tmp_path)
+
+
+def maybe_download_params(model_path):
+ if os.path.exists(model_path) or not is_link(model_path):
+ return model_path
+ else:
+ url = model_path
+ tmp_path = os.path.join(MODELS_DIR, url.split('/')[-1])
+ print('download {} to {}'.format(url, tmp_path))
+ os.makedirs(MODELS_DIR, exist_ok=True)
+ download_with_progressbar(url, tmp_path)
+ return tmp_path
+
+
+def is_link(s):
+ return s is not None and s.startswith('http')
+
+
+def confirm_model_dir_url(model_dir, default_model_dir, default_url):
+ url = default_url
+ if model_dir is None or is_link(model_dir):
+ if is_link(model_dir):
+ url = model_dir
+ file_name = url.split('/')[-1][:-4]
+ model_dir = default_model_dir
+ model_dir = os.path.join(model_dir, file_name)
+ return model_dir, url
diff --git a/ocr-studio/PaddleOCR/ppocr/utils/poly_nms.py b/ocr-studio/PaddleOCR/ppocr/utils/poly_nms.py
new file mode 100644
index 0000000000000000000000000000000000000000..9dcb3d2c2f7be2022529d5e54de357182f207cf5
--- /dev/null
+++ b/ocr-studio/PaddleOCR/ppocr/utils/poly_nms.py
@@ -0,0 +1,146 @@
+# copyright (c) 2022 PaddlePaddle Authors. All Rights Reserve.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import numpy as np
+from shapely.geometry import Polygon
+
+
+def points2polygon(points):
+ """Convert k points to 1 polygon.
+
+ Args:
+ points (ndarray or list): A ndarray or a list of shape (2k)
+ that indicates k points.
+
+ Returns:
+ polygon (Polygon): A polygon object.
+ """
+ if isinstance(points, list):
+ points = np.array(points)
+
+ assert isinstance(points, np.ndarray)
+ assert (points.size % 2 == 0) and (points.size >= 8)
+
+ point_mat = points.reshape([-1, 2])
+ return Polygon(point_mat)
+
+
+def poly_intersection(poly_det, poly_gt, buffer=0.0001):
+ """Calculate the intersection area between two polygon.
+
+ Args:
+ poly_det (Polygon): A polygon predicted by detector.
+ poly_gt (Polygon): A gt polygon.
+
+ Returns:
+ intersection_area (float): The intersection area between two polygons.
+ """
+ assert isinstance(poly_det, Polygon)
+ assert isinstance(poly_gt, Polygon)
+
+ if buffer == 0:
+ poly_inter = poly_det & poly_gt
+ else:
+ poly_inter = poly_det.buffer(buffer) & poly_gt.buffer(buffer)
+ return poly_inter.area, poly_inter
+
+
+def poly_union(poly_det, poly_gt):
+ """Calculate the union area between two polygon.
+
+ Args:
+ poly_det (Polygon): A polygon predicted by detector.
+ poly_gt (Polygon): A gt polygon.
+
+ Returns:
+ union_area (float): The union area between two polygons.
+ """
+ assert isinstance(poly_det, Polygon)
+ assert isinstance(poly_gt, Polygon)
+
+ area_det = poly_det.area
+ area_gt = poly_gt.area
+ area_inters, _ = poly_intersection(poly_det, poly_gt)
+ return area_det + area_gt - area_inters
+
+
+def valid_boundary(x, with_score=True):
+ num = len(x)
+ if num < 8:
+ return False
+ if num % 2 == 0 and (not with_score):
+ return True
+ if num % 2 == 1 and with_score:
+ return True
+
+ return False
+
+
+def boundary_iou(src, target):
+ """Calculate the IOU between two boundaries.
+
+ Args:
+ src (list): Source boundary.
+ target (list): Target boundary.
+
+ Returns:
+ iou (float): The iou between two boundaries.
+ """
+ assert valid_boundary(src, False)
+ assert valid_boundary(target, False)
+ src_poly = points2polygon(src)
+ target_poly = points2polygon(target)
+
+ return poly_iou(src_poly, target_poly)
+
+
+def poly_iou(poly_det, poly_gt):
+ """Calculate the IOU between two polygons.
+
+ Args:
+ poly_det (Polygon): A polygon predicted by detector.
+ poly_gt (Polygon): A gt polygon.
+
+ Returns:
+ iou (float): The IOU between two polygons.
+ """
+ assert isinstance(poly_det, Polygon)
+ assert isinstance(poly_gt, Polygon)
+ area_inters, _ = poly_intersection(poly_det, poly_gt)
+ area_union = poly_union(poly_det, poly_gt)
+ if area_union == 0:
+ return 0.0
+ return area_inters / area_union
+
+
+def poly_nms(polygons, threshold):
+ assert isinstance(polygons, list)
+
+ polygons = np.array(sorted(polygons, key=lambda x: x[-1]))
+
+ keep_poly = []
+ index = [i for i in range(polygons.shape[0])]
+
+ while len(index) > 0:
+ keep_poly.append(polygons[index[-1]].tolist())
+ A = polygons[index[-1]][:-1]
+ index = np.delete(index, -1)
+ iou_list = np.zeros((len(index), ))
+ for i in range(len(index)):
+ B = polygons[index[i]][:-1]
+ iou_list[i] = boundary_iou(A, B)
+ remove_index = np.where(iou_list > threshold)
+ index = np.delete(index, remove_index)
+
+ return keep_poly
diff --git a/ocr-studio/PaddleOCR/ppocr/utils/ppocr_keys_v1.txt b/ocr-studio/PaddleOCR/ppocr/utils/ppocr_keys_v1.txt
new file mode 100644
index 0000000000000000000000000000000000000000..84b885d8352226e49b1d5d791b8f43a663e246aa
--- /dev/null
+++ b/ocr-studio/PaddleOCR/ppocr/utils/ppocr_keys_v1.txt
@@ -0,0 +1,6623 @@
+'
+疗
+绚
+诚
+娇
+溜
+题
+贿
+者
+廖
+更
+纳
+加
+奉
+公
+一
+就
+汴
+计
+与
+路
+房
+原
+妇
+2
+0
+8
+-
+7
+其
+>
+:
+]
+,
+,
+骑
+刈
+全
+消
+昏
+傈
+安
+久
+钟
+嗅
+不
+影
+处
+驽
+蜿
+资
+关
+椤
+地
+瘸
+专
+问
+忖
+票
+嫉
+炎
+韵
+要
+月
+田
+节
+陂
+鄙
+捌
+备
+拳
+伺
+眼
+网
+盎
+大
+傍
+心
+东
+愉
+汇
+蹿
+科
+每
+业
+里
+航
+晏
+字
+平
+录
+先
+1
+3
+彤
+鲶
+产
+稍
+督
+腴
+有
+象
+岳
+注
+绍
+在
+泺
+文
+定
+核
+名
+水
+过
+理
+让
+偷
+率
+等
+这
+发
+”
+为
+含
+肥
+酉
+相
+鄱
+七
+编
+猥
+锛
+日
+镀
+蒂
+掰
+倒
+辆
+栾
+栗
+综
+涩
+州
+雌
+滑
+馀
+了
+机
+块
+司
+宰
+甙
+兴
+矽
+抚
+保
+用
+沧
+秩
+如
+收
+息
+滥
+页
+疑
+埠
+!
+!
+姥
+异
+橹
+钇
+向
+下
+跄
+的
+椴
+沫
+国
+绥
+獠
+报
+开
+民
+蜇
+何
+分
+凇
+长
+讥
+藏
+掏
+施
+羽
+中
+讲
+派
+嘟
+人
+提
+浼
+间
+世
+而
+古
+多
+倪
+唇
+饯
+控
+庚
+首
+赛
+蜓
+味
+断
+制
+觉
+技
+替
+艰
+溢
+潮
+夕
+钺
+外
+摘
+枋
+动
+双
+单
+啮
+户
+枇
+确
+锦
+曜
+杜
+或
+能
+效
+霜
+盒
+然
+侗
+电
+晁
+放
+步
+鹃
+新
+杖
+蜂
+吒
+濂
+瞬
+评
+总
+隍
+对
+独
+合
+也
+是
+府
+青
+天
+诲
+墙
+组
+滴
+级
+邀
+帘
+示
+已
+时
+骸
+仄
+泅
+和
+遨
+店
+雇
+疫
+持
+巍
+踮
+境
+只
+亨
+目
+鉴
+崤
+闲
+体
+泄
+杂
+作
+般
+轰
+化
+解
+迂
+诿
+蛭
+璀
+腾
+告
+版
+服
+省
+师
+小
+规
+程
+线
+海
+办
+引
+二
+桧
+牌
+砺
+洄
+裴
+修
+图
+痫
+胡
+许
+犊
+事
+郛
+基
+柴
+呼
+食
+研
+奶
+律
+蛋
+因
+葆
+察
+戏
+褒
+戒
+再
+李
+骁
+工
+貂
+油
+鹅
+章
+啄
+休
+场
+给
+睡
+纷
+豆
+器
+捎
+说
+敏
+学
+会
+浒
+设
+诊
+格
+廓
+查
+来
+霓
+室
+溆
+¢
+诡
+寥
+焕
+舜
+柒
+狐
+回
+戟
+砾
+厄
+实
+翩
+尿
+五
+入
+径
+惭
+喹
+股
+宇
+篝
+|
+;
+美
+期
+云
+九
+祺
+扮
+靠
+锝
+槌
+系
+企
+酰
+阊
+暂
+蚕
+忻
+豁
+本
+羹
+执
+条
+钦
+H
+獒
+限
+进
+季
+楦
+于
+芘
+玖
+铋
+茯
+未
+答
+粘
+括
+样
+精
+欠
+矢
+甥
+帷
+嵩
+扣
+令
+仔
+风
+皈
+行
+支
+部
+蓉
+刮
+站
+蜡
+救
+钊
+汗
+松
+嫌
+成
+可
+.
+鹤
+院
+从
+交
+政
+怕
+活
+调
+球
+局
+验
+髌
+第
+韫
+谗
+串
+到
+圆
+年
+米
+/
+*
+友
+忿
+检
+区
+看
+自
+敢
+刃
+个
+兹
+弄
+流
+留
+同
+没
+齿
+星
+聆
+轼
+湖
+什
+三
+建
+蛔
+儿
+椋
+汕
+震
+颧
+鲤
+跟
+力
+情
+璺
+铨
+陪
+务
+指
+族
+训
+滦
+鄣
+濮
+扒
+商
+箱
+十
+召
+慷
+辗
+所
+莞
+管
+护
+臭
+横
+硒
+嗓
+接
+侦
+六
+露
+党
+馋
+驾
+剖
+高
+侬
+妪
+幂
+猗
+绺
+骐
+央
+酐
+孝
+筝
+课
+徇
+缰
+门
+男
+西
+项
+句
+谙
+瞒
+秃
+篇
+教
+碲
+罚
+声
+呐
+景
+前
+富
+嘴
+鳌
+稀
+免
+朋
+啬
+睐
+去
+赈
+鱼
+住
+肩
+愕
+速
+旁
+波
+厅
+健
+茼
+厥
+鲟
+谅
+投
+攸
+炔
+数
+方
+击
+呋
+谈
+绩
+别
+愫
+僚
+躬
+鹧
+胪
+炳
+招
+喇
+膨
+泵
+蹦
+毛
+结
+5
+4
+谱
+识
+陕
+粽
+婚
+拟
+构
+且
+搜
+任
+潘
+比
+郢
+妨
+醪
+陀
+桔
+碘
+扎
+选
+哈
+骷
+楷
+亿
+明
+缆
+脯
+监
+睫
+逻
+婵
+共
+赴
+淝
+凡
+惦
+及
+达
+揖
+谩
+澹
+减
+焰
+蛹
+番
+祁
+柏
+员
+禄
+怡
+峤
+龙
+白
+叽
+生
+闯
+起
+细
+装
+谕
+竟
+聚
+钙
+上
+导
+渊
+按
+艾
+辘
+挡
+耒
+盹
+饪
+臀
+记
+邮
+蕙
+受
+各
+医
+搂
+普
+滇
+朗
+茸
+带
+翻
+酚
+(
+光
+堤
+墟
+蔷
+万
+幻
+〓
+瑙
+辈
+昧
+盏
+亘
+蛀
+吉
+铰
+请
+子
+假
+闻
+税
+井
+诩
+哨
+嫂
+好
+面
+琐
+校
+馊
+鬣
+缂
+营
+访
+炖
+占
+农
+缀
+否
+经
+钚
+棵
+趟
+张
+亟
+吏
+茶
+谨
+捻
+论
+迸
+堂
+玉
+信
+吧
+瞠
+乡
+姬
+寺
+咬
+溏
+苄
+皿
+意
+赉
+宝
+尔
+钰
+艺
+特
+唳
+踉
+都
+荣
+倚
+登
+荐
+丧
+奇
+涵
+批
+炭
+近
+符
+傩
+感
+道
+着
+菊
+虹
+仲
+众
+懈
+濯
+颞
+眺
+南
+释
+北
+缝
+标
+既
+茗
+整
+撼
+迤
+贲
+挎
+耱
+拒
+某
+妍
+卫
+哇
+英
+矶
+藩
+治
+他
+元
+领
+膜
+遮
+穗
+蛾
+飞
+荒
+棺
+劫
+么
+市
+火
+温
+拈
+棚
+洼
+转
+果
+奕
+卸
+迪
+伸
+泳
+斗
+邡
+侄
+涨
+屯
+萋
+胭
+氡
+崮
+枞
+惧
+冒
+彩
+斜
+手
+豚
+随
+旭
+淑
+妞
+形
+菌
+吲
+沱
+争
+驯
+歹
+挟
+兆
+柱
+传
+至
+包
+内
+响
+临
+红
+功
+弩
+衡
+寂
+禁
+老
+棍
+耆
+渍
+织
+害
+氵
+渑
+布
+载
+靥
+嗬
+虽
+苹
+咨
+娄
+库
+雉
+榜
+帜
+嘲
+套
+瑚
+亲
+簸
+欧
+边
+6
+腿
+旮
+抛
+吹
+瞳
+得
+镓
+梗
+厨
+继
+漾
+愣
+憨
+士
+策
+窑
+抑
+躯
+襟
+脏
+参
+贸
+言
+干
+绸
+鳄
+穷
+藜
+音
+折
+详
+)
+举
+悍
+甸
+癌
+黎
+谴
+死
+罩
+迁
+寒
+驷
+袖
+媒
+蒋
+掘
+模
+纠
+恣
+观
+祖
+蛆
+碍
+位
+稿
+主
+澧
+跌
+筏
+京
+锏
+帝
+贴
+证
+糠
+才
+黄
+鲸
+略
+炯
+饱
+四
+出
+园
+犀
+牧
+容
+汉
+杆
+浈
+汰
+瑷
+造
+虫
+瘩
+怪
+驴
+济
+应
+花
+沣
+谔
+夙
+旅
+价
+矿
+以
+考
+s
+u
+呦
+晒
+巡
+茅
+准
+肟
+瓴
+詹
+仟
+褂
+译
+桌
+混
+宁
+怦
+郑
+抿
+些
+余
+鄂
+饴
+攒
+珑
+群
+阖
+岔
+琨
+藓
+预
+环
+洮
+岌
+宀
+杲
+瀵
+最
+常
+囡
+周
+踊
+女
+鼓
+袭
+喉
+简
+范
+薯
+遐
+疏
+粱
+黜
+禧
+法
+箔
+斤
+遥
+汝
+奥
+直
+贞
+撑
+置
+绱
+集
+她
+馅
+逗
+钧
+橱
+魉
+[
+恙
+躁
+唤
+9
+旺
+膘
+待
+脾
+惫
+购
+吗
+依
+盲
+度
+瘿
+蠖
+俾
+之
+镗
+拇
+鲵
+厝
+簧
+续
+款
+展
+啃
+表
+剔
+品
+钻
+腭
+损
+清
+锶
+统
+涌
+寸
+滨
+贪
+链
+吠
+冈
+伎
+迥
+咏
+吁
+览
+防
+迅
+失
+汾
+阔
+逵
+绀
+蔑
+列
+川
+凭
+努
+熨
+揪
+利
+俱
+绉
+抢
+鸨
+我
+即
+责
+膦
+易
+毓
+鹊
+刹
+玷
+岿
+空
+嘞
+绊
+排
+术
+估
+锷
+违
+们
+苟
+铜
+播
+肘
+件
+烫
+审
+鲂
+广
+像
+铌
+惰
+铟
+巳
+胍
+鲍
+康
+憧
+色
+恢
+想
+拷
+尤
+疳
+知
+S
+Y
+F
+D
+A
+峄
+裕
+帮
+握
+搔
+氐
+氘
+难
+墒
+沮
+雨
+叁
+缥
+悴
+藐
+湫
+娟
+苑
+稠
+颛
+簇
+后
+阕
+闭
+蕤
+缚
+怎
+佞
+码
+嘤
+蔡
+痊
+舱
+螯
+帕
+赫
+昵
+升
+烬
+岫
+、
+疵
+蜻
+髁
+蕨
+隶
+烛
+械
+丑
+盂
+梁
+强
+鲛
+由
+拘
+揉
+劭
+龟
+撤
+钩
+呕
+孛
+费
+妻
+漂
+求
+阑
+崖
+秤
+甘
+通
+深
+补
+赃
+坎
+床
+啪
+承
+吼
+量
+暇
+钼
+烨
+阂
+擎
+脱
+逮
+称
+P
+神
+属
+矗
+华
+届
+狍
+葑
+汹
+育
+患
+窒
+蛰
+佼
+静
+槎
+运
+鳗
+庆
+逝
+曼
+疱
+克
+代
+官
+此
+麸
+耧
+蚌
+晟
+例
+础
+榛
+副
+测
+唰
+缢
+迹
+灬
+霁
+身
+岁
+赭
+扛
+又
+菡
+乜
+雾
+板
+读
+陷
+徉
+贯
+郁
+虑
+变
+钓
+菜
+圾
+现
+琢
+式
+乐
+维
+渔
+浜
+左
+吾
+脑
+钡
+警
+T
+啵
+拴
+偌
+漱
+湿
+硕
+止
+骼
+魄
+积
+燥
+联
+踢
+玛
+则
+窿
+见
+振
+畿
+送
+班
+钽
+您
+赵
+刨
+印
+讨
+踝
+籍
+谡
+舌
+崧
+汽
+蔽
+沪
+酥
+绒
+怖
+财
+帖
+肱
+私
+莎
+勋
+羔
+霸
+励
+哼
+帐
+将
+帅
+渠
+纪
+婴
+娩
+岭
+厘
+滕
+吻
+伤
+坝
+冠
+戊
+隆
+瘁
+介
+涧
+物
+黍
+并
+姗
+奢
+蹑
+掣
+垸
+锴
+命
+箍
+捉
+病
+辖
+琰
+眭
+迩
+艘
+绌
+繁
+寅
+若
+毋
+思
+诉
+类
+诈
+燮
+轲
+酮
+狂
+重
+反
+职
+筱
+县
+委
+磕
+绣
+奖
+晋
+濉
+志
+徽
+肠
+呈
+獐
+坻
+口
+片
+碰
+几
+村
+柿
+劳
+料
+获
+亩
+惕
+晕
+厌
+号
+罢
+池
+正
+鏖
+煨
+家
+棕
+复
+尝
+懋
+蜥
+锅
+岛
+扰
+队
+坠
+瘾
+钬
+@
+卧
+疣
+镇
+譬
+冰
+彷
+频
+黯
+据
+垄
+采
+八
+缪
+瘫
+型
+熹
+砰
+楠
+襁
+箐
+但
+嘶
+绳
+啤
+拍
+盥
+穆
+傲
+洗
+盯
+塘
+怔
+筛
+丿
+台
+恒
+喂
+葛
+永
+¥
+烟
+酒
+桦
+书
+砂
+蚝
+缉
+态
+瀚
+袄
+圳
+轻
+蛛
+超
+榧
+遛
+姒
+奘
+铮
+右
+荽
+望
+偻
+卡
+丶
+氰
+附
+做
+革
+索
+戚
+坨
+桷
+唁
+垅
+榻
+岐
+偎
+坛
+莨
+山
+殊
+微
+骇
+陈
+爨
+推
+嗝
+驹
+澡
+藁
+呤
+卤
+嘻
+糅
+逛
+侵
+郓
+酌
+德
+摇
+※
+鬃
+被
+慨
+殡
+羸
+昌
+泡
+戛
+鞋
+河
+宪
+沿
+玲
+鲨
+翅
+哽
+源
+铅
+语
+照
+邯
+址
+荃
+佬
+顺
+鸳
+町
+霭
+睾
+瓢
+夸
+椁
+晓
+酿
+痈
+咔
+侏
+券
+噎
+湍
+签
+嚷
+离
+午
+尚
+社
+锤
+背
+孟
+使
+浪
+缦
+潍
+鞅
+军
+姹
+驶
+笑
+鳟
+鲁
+》
+孽
+钜
+绿
+洱
+礴
+焯
+椰
+颖
+囔
+乌
+孔
+巴
+互
+性
+椽
+哞
+聘
+昨
+早
+暮
+胶
+炀
+隧
+低
+彗
+昝
+铁
+呓
+氽
+藉
+喔
+癖
+瑗
+姨
+权
+胱
+韦
+堑
+蜜
+酋
+楝
+砝
+毁
+靓
+歙
+锲
+究
+屋
+喳
+骨
+辨
+碑
+武
+鸠
+宫
+辜
+烊
+适
+坡
+殃
+培
+佩
+供
+走
+蜈
+迟
+翼
+况
+姣
+凛
+浔
+吃
+飘
+债
+犟
+金
+促
+苛
+崇
+坂
+莳
+畔
+绂
+兵
+蠕
+斋
+根
+砍
+亢
+欢
+恬
+崔
+剁
+餐
+榫
+快
+扶
+‖
+濒
+缠
+鳜
+当
+彭
+驭
+浦
+篮
+昀
+锆
+秸
+钳
+弋
+娣
+瞑
+夷
+龛
+苫
+拱
+致
+%
+嵊
+障
+隐
+弑
+初
+娓
+抉
+汩
+累
+蓖
+"
+唬
+助
+苓
+昙
+押
+毙
+破
+城
+郧
+逢
+嚏
+獭
+瞻
+溱
+婿
+赊
+跨
+恼
+璧
+萃
+姻
+貉
+灵
+炉
+密
+氛
+陶
+砸
+谬
+衔
+点
+琛
+沛
+枳
+层
+岱
+诺
+脍
+榈
+埂
+征
+冷
+裁
+打
+蹴
+素
+瘘
+逞
+蛐
+聊
+激
+腱
+萘
+踵
+飒
+蓟
+吆
+取
+咙
+簋
+涓
+矩
+曝
+挺
+揣
+座
+你
+史
+舵
+焱
+尘
+苏
+笈
+脚
+溉
+榨
+诵
+樊
+邓
+焊
+义
+庶
+儋
+蟋
+蒲
+赦
+呷
+杞
+诠
+豪
+还
+试
+颓
+茉
+太
+除
+紫
+逃
+痴
+草
+充
+鳕
+珉
+祗
+墨
+渭
+烩
+蘸
+慕
+璇
+镶
+穴
+嵘
+恶
+骂
+险
+绋
+幕
+碉
+肺
+戳
+刘
+潞
+秣
+纾
+潜
+銮
+洛
+须
+罘
+销
+瘪
+汞
+兮
+屉
+r
+林
+厕
+质
+探
+划
+狸
+殚
+善
+煊
+烹
+〒
+锈
+逯
+宸
+辍
+泱
+柚
+袍
+远
+蹋
+嶙
+绝
+峥
+娥
+缍
+雀
+徵
+认
+镱
+谷
+=
+贩
+勉
+撩
+鄯
+斐
+洋
+非
+祚
+泾
+诒
+饿
+撬
+威
+晷
+搭
+芍
+锥
+笺
+蓦
+候
+琊
+档
+礁
+沼
+卵
+荠
+忑
+朝
+凹
+瑞
+头
+仪
+弧
+孵
+畏
+铆
+突
+衲
+车
+浩
+气
+茂
+悖
+厢
+枕
+酝
+戴
+湾
+邹
+飚
+攘
+锂
+写
+宵
+翁
+岷
+无
+喜
+丈
+挑
+嗟
+绛
+殉
+议
+槽
+具
+醇
+淞
+笃
+郴
+阅
+饼
+底
+壕
+砚
+弈
+询
+缕
+庹
+翟
+零
+筷
+暨
+舟
+闺
+甯
+撞
+麂
+茌
+蔼
+很
+珲
+捕
+棠
+角
+阉
+媛
+娲
+诽
+剿
+尉
+爵
+睬
+韩
+诰
+匣
+危
+糍
+镯
+立
+浏
+阳
+少
+盆
+舔
+擘
+匪
+申
+尬
+铣
+旯
+抖
+赘
+瓯
+居
+ˇ
+哮
+游
+锭
+茏
+歌
+坏
+甚
+秒
+舞
+沙
+仗
+劲
+潺
+阿
+燧
+郭
+嗖
+霏
+忠
+材
+奂
+耐
+跺
+砀
+输
+岖
+媳
+氟
+极
+摆
+灿
+今
+扔
+腻
+枝
+奎
+药
+熄
+吨
+话
+q
+额
+慑
+嘌
+协
+喀
+壳
+埭
+视
+著
+於
+愧
+陲
+翌
+峁
+颅
+佛
+腹
+聋
+侯
+咎
+叟
+秀
+颇
+存
+较
+罪
+哄
+岗
+扫
+栏
+钾
+羌
+己
+璨
+枭
+霉
+煌
+涸
+衿
+键
+镝
+益
+岢
+奏
+连
+夯
+睿
+冥
+均
+糖
+狞
+蹊
+稻
+爸
+刿
+胥
+煜
+丽
+肿
+璃
+掸
+跚
+灾
+垂
+樾
+濑
+乎
+莲
+窄
+犹
+撮
+战
+馄
+软
+络
+显
+鸢
+胸
+宾
+妲
+恕
+埔
+蝌
+份
+遇
+巧
+瞟
+粒
+恰
+剥
+桡
+博
+讯
+凯
+堇
+阶
+滤
+卖
+斌
+骚
+彬
+兑
+磺
+樱
+舷
+两
+娱
+福
+仃
+差
+找
+桁
+÷
+净
+把
+阴
+污
+戬
+雷
+碓
+蕲
+楚
+罡
+焖
+抽
+妫
+咒
+仑
+闱
+尽
+邑
+菁
+爱
+贷
+沥
+鞑
+牡
+嗉
+崴
+骤
+塌
+嗦
+订
+拮
+滓
+捡
+锻
+次
+坪
+杩
+臃
+箬
+融
+珂
+鹗
+宗
+枚
+降
+鸬
+妯
+阄
+堰
+盐
+毅
+必
+杨
+崃
+俺
+甬
+状
+莘
+货
+耸
+菱
+腼
+铸
+唏
+痤
+孚
+澳
+懒
+溅
+翘
+疙
+杷
+淼
+缙
+骰
+喊
+悉
+砻
+坷
+艇
+赁
+界
+谤
+纣
+宴
+晃
+茹
+归
+饭
+梢
+铡
+街
+抄
+肼
+鬟
+苯
+颂
+撷
+戈
+炒
+咆
+茭
+瘙
+负
+仰
+客
+琉
+铢
+封
+卑
+珥
+椿
+镧
+窨
+鬲
+寿
+御
+袤
+铃
+萎
+砖
+餮
+脒
+裳
+肪
+孕
+嫣
+馗
+嵇
+恳
+氯
+江
+石
+褶
+冢
+祸
+阻
+狈
+羞
+银
+靳
+透
+咳
+叼
+敷
+芷
+啥
+它
+瓤
+兰
+痘
+懊
+逑
+肌
+往
+捺
+坊
+甩
+呻
+〃
+沦
+忘
+膻
+祟
+菅
+剧
+崆
+智
+坯
+臧
+霍
+墅
+攻
+眯
+倘
+拢
+骠
+铐
+庭
+岙
+瓠
+′
+缺
+泥
+迢
+捶
+?
+?
+郏
+喙
+掷
+沌
+纯
+秘
+种
+听
+绘
+固
+螨
+团
+香
+盗
+妒
+埚
+蓝
+拖
+旱
+荞
+铀
+血
+遏
+汲
+辰
+叩
+拽
+幅
+硬
+惶
+桀
+漠
+措
+泼
+唑
+齐
+肾
+念
+酱
+虚
+屁
+耶
+旗
+砦
+闵
+婉
+馆
+拭
+绅
+韧
+忏
+窝
+醋
+葺
+顾
+辞
+倜
+堆
+辋
+逆
+玟
+贱
+疾
+董
+惘
+倌
+锕
+淘
+嘀
+莽
+俭
+笏
+绑
+鲷
+杈
+择
+蟀
+粥
+嗯
+驰
+逾
+案
+谪
+褓
+胫
+哩
+昕
+颚
+鲢
+绠
+躺
+鹄
+崂
+儒
+俨
+丝
+尕
+泌
+啊
+萸
+彰
+幺
+吟
+骄
+苣
+弦
+脊
+瑰
+〈
+诛
+镁
+析
+闪
+剪
+侧
+哟
+框
+螃
+守
+嬗
+燕
+狭
+铈
+缮
+概
+迳
+痧
+鲲
+俯
+售
+笼
+痣
+扉
+挖
+满
+咋
+援
+邱
+扇
+歪
+便
+玑
+绦
+峡
+蛇
+叨
+〖
+泽
+胃
+斓
+喋
+怂
+坟
+猪
+该
+蚬
+炕
+弥
+赞
+棣
+晔
+娠
+挲
+狡
+创
+疖
+铕
+镭
+稷
+挫
+弭
+啾
+翔
+粉
+履
+苘
+哦
+楼
+秕
+铂
+土
+锣
+瘟
+挣
+栉
+习
+享
+桢
+袅
+磨
+桂
+谦
+延
+坚
+蔚
+噗
+署
+谟
+猬
+钎
+恐
+嬉
+雒
+倦
+衅
+亏
+璩
+睹
+刻
+殿
+王
+算
+雕
+麻
+丘
+柯
+骆
+丸
+塍
+谚
+添
+鲈
+垓
+桎
+蚯
+芥
+予
+飕
+镦
+谌
+窗
+醚
+菀
+亮
+搪
+莺
+蒿
+羁
+足
+J
+真
+轶
+悬
+衷
+靛
+翊
+掩
+哒
+炅
+掐
+冼
+妮
+l
+谐
+稚
+荆
+擒
+犯
+陵
+虏
+浓
+崽
+刍
+陌
+傻
+孜
+千
+靖
+演
+矜
+钕
+煽
+杰
+酗
+渗
+伞
+栋
+俗
+泫
+戍
+罕
+沾
+疽
+灏
+煦
+芬
+磴
+叱
+阱
+榉
+湃
+蜀
+叉
+醒
+彪
+租
+郡
+篷
+屎
+良
+垢
+隗
+弱
+陨
+峪
+砷
+掴
+颁
+胎
+雯
+绵
+贬
+沐
+撵
+隘
+篙
+暖
+曹
+陡
+栓
+填
+臼
+彦
+瓶
+琪
+潼
+哪
+鸡
+摩
+啦
+俟
+锋
+域
+耻
+蔫
+疯
+纹
+撇
+毒
+绶
+痛
+酯
+忍
+爪
+赳
+歆
+嘹
+辕
+烈
+册
+朴
+钱
+吮
+毯
+癜
+娃
+谀
+邵
+厮
+炽
+璞
+邃
+丐
+追
+词
+瓒
+忆
+轧
+芫
+谯
+喷
+弟
+半
+冕
+裙
+掖
+墉
+绮
+寝
+苔
+势
+顷
+褥
+切
+衮
+君
+佳
+嫒
+蚩
+霞
+佚
+洙
+逊
+镖
+暹
+唛
+&
+殒
+顶
+碗
+獗
+轭
+铺
+蛊
+废
+恹
+汨
+崩
+珍
+那
+杵
+曲
+纺
+夏
+薰
+傀
+闳
+淬
+姘
+舀
+拧
+卷
+楂
+恍
+讪
+厩
+寮
+篪
+赓
+乘
+灭
+盅
+鞣
+沟
+慎
+挂
+饺
+鼾
+杳
+树
+缨
+丛
+絮
+娌
+臻
+嗳
+篡
+侩
+述
+衰
+矛
+圈
+蚜
+匕
+筹
+匿
+濞
+晨
+叶
+骋
+郝
+挚
+蚴
+滞
+增
+侍
+描
+瓣
+吖
+嫦
+蟒
+匾
+圣
+赌
+毡
+癞
+恺
+百
+曳
+需
+篓
+肮
+庖
+帏
+卿
+驿
+遗
+蹬
+鬓
+骡
+歉
+芎
+胳
+屐
+禽
+烦
+晌
+寄
+媾
+狄
+翡
+苒
+船
+廉
+终
+痞
+殇
+々
+畦
+饶
+改
+拆
+悻
+萄
+£
+瓿
+乃
+訾
+桅
+匮
+溧
+拥
+纱
+铍
+骗
+蕃
+龋
+缬
+父
+佐
+疚
+栎
+醍
+掳
+蓄
+x
+惆
+颜
+鲆
+榆
+〔
+猎
+敌
+暴
+谥
+鲫
+贾
+罗
+玻
+缄
+扦
+芪
+癣
+落
+徒
+臾
+恿
+猩
+托
+邴
+肄
+牵
+春
+陛
+耀
+刊
+拓
+蓓
+邳
+堕
+寇
+枉
+淌
+啡
+湄
+兽
+酷
+萼
+碚
+濠
+萤
+夹
+旬
+戮
+梭
+琥
+椭
+昔
+勺
+蜊
+绐
+晚
+孺
+僵
+宣
+摄
+冽
+旨
+萌
+忙
+蚤
+眉
+噼
+蟑
+付
+契
+瓜
+悼
+颡
+壁
+曾
+窕
+颢
+澎
+仿
+俑
+浑
+嵌
+浣
+乍
+碌
+褪
+乱
+蔟
+隙
+玩
+剐
+葫
+箫
+纲
+围
+伐
+决
+伙
+漩
+瑟
+刑
+肓
+镳
+缓
+蹭
+氨
+皓
+典
+畲
+坍
+铑
+檐
+塑
+洞
+倬
+储
+胴
+淳
+戾
+吐
+灼
+惺
+妙
+毕
+珐
+缈
+虱
+盖
+羰
+鸿
+磅
+谓
+髅
+娴
+苴
+唷
+蚣
+霹
+抨
+贤
+唠
+犬
+誓
+逍
+庠
+逼
+麓
+籼
+釉
+呜
+碧
+秧
+氩
+摔
+霄
+穸
+纨
+辟
+妈
+映
+完
+牛
+缴
+嗷
+炊
+恩
+荔
+茆
+掉
+紊
+慌
+莓
+羟
+阙
+萁
+磐
+另
+蕹
+辱
+鳐
+湮
+吡
+吩
+唐
+睦
+垠
+舒
+圜
+冗
+瞿
+溺
+芾
+囱
+匠
+僳
+汐
+菩
+饬
+漓
+黑
+霰
+浸
+濡
+窥
+毂
+蒡
+兢
+驻
+鹉
+芮
+诙
+迫
+雳
+厂
+忐
+臆
+猴
+鸣
+蚪
+栈
+箕
+羡
+渐
+莆
+捍
+眈
+哓
+趴
+蹼
+埕
+嚣
+骛
+宏
+淄
+斑
+噜
+严
+瑛
+垃
+椎
+诱
+压
+庾
+绞
+焘
+廿
+抡
+迄
+棘
+夫
+纬
+锹
+眨
+瞌
+侠
+脐
+竞
+瀑
+孳
+骧
+遁
+姜
+颦
+荪
+滚
+萦
+伪
+逸
+粳
+爬
+锁
+矣
+役
+趣
+洒
+颔
+诏
+逐
+奸
+甭
+惠
+攀
+蹄
+泛
+尼
+拼
+阮
+鹰
+亚
+颈
+惑
+勒
+〉
+际
+肛
+爷
+刚
+钨
+丰
+养
+冶
+鲽
+辉
+蔻
+画
+覆
+皴
+妊
+麦
+返
+醉
+皂
+擀
+〗
+酶
+凑
+粹
+悟
+诀
+硖
+港
+卜
+z
+杀
+涕
+±
+舍
+铠
+抵
+弛
+段
+敝
+镐
+奠
+拂
+轴
+跛
+袱
+e
+t
+沉
+菇
+俎
+薪
+峦
+秭
+蟹
+历
+盟
+菠
+寡
+液
+肢
+喻
+染
+裱
+悱
+抱
+氙
+赤
+捅
+猛
+跑
+氮
+谣
+仁
+尺
+辊
+窍
+烙
+衍
+架
+擦
+倏
+璐
+瑁
+币
+楞
+胖
+夔
+趸
+邛
+惴
+饕
+虔
+蝎
+§
+哉
+贝
+宽
+辫
+炮
+扩
+饲
+籽
+魏
+菟
+锰
+伍
+猝
+末
+琳
+哚
+蛎
+邂
+呀
+姿
+鄞
+却
+歧
+仙
+恸
+椐
+森
+牒
+寤
+袒
+婆
+虢
+雅
+钉
+朵
+贼
+欲
+苞
+寰
+故
+龚
+坭
+嘘
+咫
+礼
+硷
+兀
+睢
+汶
+’
+铲
+烧
+绕
+诃
+浃
+钿
+哺
+柜
+讼
+颊
+璁
+腔
+洽
+咐
+脲
+簌
+筠
+镣
+玮
+鞠
+谁
+兼
+姆
+挥
+梯
+蝴
+谘
+漕
+刷
+躏
+宦
+弼
+b
+垌
+劈
+麟
+莉
+揭
+笙
+渎
+仕
+嗤
+仓
+配
+怏
+抬
+错
+泯
+镊
+孰
+猿
+邪
+仍
+秋
+鼬
+壹
+歇
+吵
+炼
+<
+尧
+射
+柬
+廷
+胧
+霾
+凳
+隋
+肚
+浮
+梦
+祥
+株
+堵
+退
+L
+鹫
+跎
+凶
+毽
+荟
+炫
+栩
+玳
+甜
+沂
+鹿
+顽
+伯
+爹
+赔
+蛴
+徐
+匡
+欣
+狰
+缸
+雹
+蟆
+疤
+默
+沤
+啜
+痂
+衣
+禅
+w
+i
+h
+辽
+葳
+黝
+钗
+停
+沽
+棒
+馨
+颌
+肉
+吴
+硫
+悯
+劾
+娈
+马
+啧
+吊
+悌
+镑
+峭
+帆
+瀣
+涉
+咸
+疸
+滋
+泣
+翦
+拙
+癸
+钥
+蜒
++
+尾
+庄
+凝
+泉
+婢
+渴
+谊
+乞
+陆
+锉
+糊
+鸦
+淮
+I
+B
+N
+晦
+弗
+乔
+庥
+葡
+尻
+席
+橡
+傣
+渣
+拿
+惩
+麋
+斛
+缃
+矮
+蛏
+岘
+鸽
+姐
+膏
+催
+奔
+镒
+喱
+蠡
+摧
+钯
+胤
+柠
+拐
+璋
+鸥
+卢
+荡
+倾
+^
+_
+珀
+逄
+萧
+塾
+掇
+贮
+笆
+聂
+圃
+冲
+嵬
+M
+滔
+笕
+值
+炙
+偶
+蜱
+搐
+梆
+汪
+蔬
+腑
+鸯
+蹇
+敞
+绯
+仨
+祯
+谆
+梧
+糗
+鑫
+啸
+豺
+囹
+猾
+巢
+柄
+瀛
+筑
+踌
+沭
+暗
+苁
+鱿
+蹉
+脂
+蘖
+牢
+热
+木
+吸
+溃
+宠
+序
+泞
+偿
+拜
+檩
+厚
+朐
+毗
+螳
+吞
+媚
+朽
+担
+蝗
+橘
+畴
+祈
+糟
+盱
+隼
+郜
+惜
+珠
+裨
+铵
+焙
+琚
+唯
+咚
+噪
+骊
+丫
+滢
+勤
+棉
+呸
+咣
+淀
+隔
+蕾
+窈
+饨
+挨
+煅
+短
+匙
+粕
+镜
+赣
+撕
+墩
+酬
+馁
+豌
+颐
+抗
+酣
+氓
+佑
+搁
+哭
+递
+耷
+涡
+桃
+贻
+碣
+截
+瘦
+昭
+镌
+蔓
+氚
+甲
+猕
+蕴
+蓬
+散
+拾
+纛
+狼
+猷
+铎
+埋
+旖
+矾
+讳
+囊
+糜
+迈
+粟
+蚂
+紧
+鲳
+瘢
+栽
+稼
+羊
+锄
+斟
+睁
+桥
+瓮
+蹙
+祉
+醺
+鼻
+昱
+剃
+跳
+篱
+跷
+蒜
+翎
+宅
+晖
+嗑
+壑
+峻
+癫
+屏
+狠
+陋
+袜
+途
+憎
+祀
+莹
+滟
+佶
+溥
+臣
+约
+盛
+峰
+磁
+慵
+婪
+拦
+莅
+朕
+鹦
+粲
+裤
+哎
+疡
+嫖
+琵
+窟
+堪
+谛
+嘉
+儡
+鳝
+斩
+郾
+驸
+酊
+妄
+胜
+贺
+徙
+傅
+噌
+钢
+栅
+庇
+恋
+匝
+巯
+邈
+尸
+锚
+粗
+佟
+蛟
+薹
+纵
+蚊
+郅
+绢
+锐
+苗
+俞
+篆
+淆
+膀
+鲜
+煎
+诶
+秽
+寻
+涮
+刺
+怀
+噶
+巨
+褰
+魅
+灶
+灌
+桉
+藕
+谜
+舸
+薄
+搀
+恽
+借
+牯
+痉
+渥
+愿
+亓
+耘
+杠
+柩
+锔
+蚶
+钣
+珈
+喘
+蹒
+幽
+赐
+稗
+晤
+莱
+泔
+扯
+肯
+菪
+裆
+腩
+豉
+疆
+骜
+腐
+倭
+珏
+唔
+粮
+亡
+润
+慰
+伽
+橄
+玄
+誉
+醐
+胆
+龊
+粼
+塬
+陇
+彼
+削
+嗣
+绾
+芽
+妗
+垭
+瘴
+爽
+薏
+寨
+龈
+泠
+弹
+赢
+漪
+猫
+嘧
+涂
+恤
+圭
+茧
+烽
+屑
+痕
+巾
+赖
+荸
+凰
+腮
+畈
+亵
+蹲
+偃
+苇
+澜
+艮
+换
+骺
+烘
+苕
+梓
+颉
+肇
+哗
+悄
+氤
+涠
+葬
+屠
+鹭
+植
+竺
+佯
+诣
+鲇
+瘀
+鲅
+邦
+移
+滁
+冯
+耕
+癔
+戌
+茬
+沁
+巩
+悠
+湘
+洪
+痹
+锟
+循
+谋
+腕
+鳃
+钠
+捞
+焉
+迎
+碱
+伫
+急
+榷
+奈
+邝
+卯
+辄
+皲
+卟
+醛
+畹
+忧
+稳
+雄
+昼
+缩
+阈
+睑
+扌
+耗
+曦
+涅
+捏
+瞧
+邕
+淖
+漉
+铝
+耦
+禹
+湛
+喽
+莼
+琅
+诸
+苎
+纂
+硅
+始
+嗨
+傥
+燃
+臂
+赅
+嘈
+呆
+贵
+屹
+壮
+肋
+亍
+蚀
+卅
+豹
+腆
+邬
+迭
+浊
+}
+童
+螂
+捐
+圩
+勐
+触
+寞
+汊
+壤
+荫
+膺
+渌
+芳
+懿
+遴
+螈
+泰
+蓼
+蛤
+茜
+舅
+枫
+朔
+膝
+眙
+避
+梅
+判
+鹜
+璜
+牍
+缅
+垫
+藻
+黔
+侥
+惚
+懂
+踩
+腰
+腈
+札
+丞
+唾
+慈
+顿
+摹
+荻
+琬
+~
+斧
+沈
+滂
+胁
+胀
+幄
+莜
+Z
+匀
+鄄
+掌
+绰
+茎
+焚
+赋
+萱
+谑
+汁
+铒
+瞎
+夺
+蜗
+野
+娆
+冀
+弯
+篁
+懵
+灞
+隽
+芡
+脘
+俐
+辩
+芯
+掺
+喏
+膈
+蝈
+觐
+悚
+踹
+蔗
+熠
+鼠
+呵
+抓
+橼
+峨
+畜
+缔
+禾
+崭
+弃
+熊
+摒
+凸
+拗
+穹
+蒙
+抒
+祛
+劝
+闫
+扳
+阵
+醌
+踪
+喵
+侣
+搬
+仅
+荧
+赎
+蝾
+琦
+买
+婧
+瞄
+寓
+皎
+冻
+赝
+箩
+莫
+瞰
+郊
+笫
+姝
+筒
+枪
+遣
+煸
+袋
+舆
+痱
+涛
+母
+〇
+启
+践
+耙
+绲
+盘
+遂
+昊
+搞
+槿
+诬
+纰
+泓
+惨
+檬
+亻
+越
+C
+o
+憩
+熵
+祷
+钒
+暧
+塔
+阗
+胰
+咄
+娶
+魔
+琶
+钞
+邻
+扬
+杉
+殴
+咽
+弓
+〆
+髻
+】
+吭
+揽
+霆
+拄
+殖
+脆
+彻
+岩
+芝
+勃
+辣
+剌
+钝
+嘎
+甄
+佘
+皖
+伦
+授
+徕
+憔
+挪
+皇
+庞
+稔
+芜
+踏
+溴
+兖
+卒
+擢
+饥
+鳞
+煲
+‰
+账
+颗
+叻
+斯
+捧
+鳍
+琮
+讹
+蛙
+纽
+谭
+酸
+兔
+莒
+睇
+伟
+觑
+羲
+嗜
+宜
+褐
+旎
+辛
+卦
+诘
+筋
+鎏
+溪
+挛
+熔
+阜
+晰
+鳅
+丢
+奚
+灸
+呱
+献
+陉
+黛
+鸪
+甾
+萨
+疮
+拯
+洲
+疹
+辑
+叙
+恻
+谒
+允
+柔
+烂
+氏
+逅
+漆
+拎
+惋
+扈
+湟
+纭
+啕
+掬
+擞
+哥
+忽
+涤
+鸵
+靡
+郗
+瓷
+扁
+廊
+怨
+雏
+钮
+敦
+E
+懦
+憋
+汀
+拚
+啉
+腌
+岸
+f
+痼
+瞅
+尊
+咀
+眩
+飙
+忌
+仝
+迦
+熬
+毫
+胯
+篑
+茄
+腺
+凄
+舛
+碴
+锵
+诧
+羯
+後
+漏
+汤
+宓
+仞
+蚁
+壶
+谰
+皑
+铄
+棰
+罔
+辅
+晶
+苦
+牟
+闽
+\
+烃
+饮
+聿
+丙
+蛳
+朱
+煤
+涔
+鳖
+犁
+罐
+荼
+砒
+淦
+妤
+黏
+戎
+孑
+婕
+瑾
+戢
+钵
+枣
+捋
+砥
+衩
+狙
+桠
+稣
+阎
+肃
+梏
+诫
+孪
+昶
+婊
+衫
+嗔
+侃
+塞
+蜃
+樵
+峒
+貌
+屿
+欺
+缫
+阐
+栖
+诟
+珞
+荭
+吝
+萍
+嗽
+恂
+啻
+蜴
+磬
+峋
+俸
+豫
+谎
+徊
+镍
+韬
+魇
+晴
+U
+囟
+猜
+蛮
+坐
+囿
+伴
+亭
+肝
+佗
+蝠
+妃
+胞
+滩
+榴
+氖
+垩
+苋
+砣
+扪
+馏
+姓
+轩
+厉
+夥
+侈
+禀
+垒
+岑
+赏
+钛
+辐
+痔
+披
+纸
+碳
+“
+坞
+蠓
+挤
+荥
+沅
+悔
+铧
+帼
+蒌
+蝇
+a
+p
+y
+n
+g
+哀
+浆
+瑶
+凿
+桶
+馈
+皮
+奴
+苜
+佤
+伶
+晗
+铱
+炬
+优
+弊
+氢
+恃
+甫
+攥
+端
+锌
+灰
+稹
+炝
+曙
+邋
+亥
+眶
+碾
+拉
+萝
+绔
+捷
+浍
+腋
+姑
+菖
+凌
+涞
+麽
+锢
+桨
+潢
+绎
+镰
+殆
+锑
+渝
+铬
+困
+绽
+觎
+匈
+糙
+暑
+裹
+鸟
+盔
+肽
+迷
+綦
+『
+亳
+佝
+俘
+钴
+觇
+骥
+仆
+疝
+跪
+婶
+郯
+瀹
+唉
+脖
+踞
+针
+晾
+忒
+扼
+瞩
+叛
+椒
+疟
+嗡
+邗
+肆
+跆
+玫
+忡
+捣
+咧
+唆
+艄
+蘑
+潦
+笛
+阚
+沸
+泻
+掊
+菽
+贫
+斥
+髂
+孢
+镂
+赂
+麝
+鸾
+屡
+衬
+苷
+恪
+叠
+希
+粤
+爻
+喝
+茫
+惬
+郸
+绻
+庸
+撅
+碟
+宄
+妹
+膛
+叮
+饵
+崛
+嗲
+椅
+冤
+搅
+咕
+敛
+尹
+垦
+闷
+蝉
+霎
+勰
+败
+蓑
+泸
+肤
+鹌
+幌
+焦
+浠
+鞍
+刁
+舰
+乙
+竿
+裔
+。
+茵
+函
+伊
+兄
+丨
+娜
+匍
+謇
+莪
+宥
+似
+蝽
+翳
+酪
+翠
+粑
+薇
+祢
+骏
+赠
+叫
+Q
+噤
+噻
+竖
+芗
+莠
+潭
+俊
+羿
+耜
+O
+郫
+趁
+嗪
+囚
+蹶
+芒
+洁
+笋
+鹑
+敲
+硝
+啶
+堡
+渲
+揩
+』
+携
+宿
+遒
+颍
+扭
+棱
+割
+萜
+蔸
+葵
+琴
+捂
+饰
+衙
+耿
+掠
+募
+岂
+窖
+涟
+蔺
+瘤
+柞
+瞪
+怜
+匹
+距
+楔
+炜
+哆
+秦
+缎
+幼
+茁
+绪
+痨
+恨
+楸
+娅
+瓦
+桩
+雪
+嬴
+伏
+榔
+妥
+铿
+拌
+眠
+雍
+缇
+‘
+卓
+搓
+哌
+觞
+噩
+屈
+哧
+髓
+咦
+巅
+娑
+侑
+淫
+膳
+祝
+勾
+姊
+莴
+胄
+疃
+薛
+蜷
+胛
+巷
+芙
+芋
+熙
+闰
+勿
+窃
+狱
+剩
+钏
+幢
+陟
+铛
+慧
+靴
+耍
+k
+浙
+浇
+飨
+惟
+绗
+祜
+澈
+啼
+咪
+磷
+摞
+诅
+郦
+抹
+跃
+壬
+吕
+肖
+琏
+颤
+尴
+剡
+抠
+凋
+赚
+泊
+津
+宕
+殷
+倔
+氲
+漫
+邺
+涎
+怠
+$
+垮
+荬
+遵
+俏
+叹
+噢
+饽
+蜘
+孙
+筵
+疼
+鞭
+羧
+牦
+箭
+潴
+c
+眸
+祭
+髯
+啖
+坳
+愁
+芩
+驮
+倡
+巽
+穰
+沃
+胚
+怒
+凤
+槛
+剂
+趵
+嫁
+v
+邢
+灯
+鄢
+桐
+睽
+檗
+锯
+槟
+婷
+嵋
+圻
+诗
+蕈
+颠
+遭
+痢
+芸
+怯
+馥
+竭
+锗
+徜
+恭
+遍
+籁
+剑
+嘱
+苡
+龄
+僧
+桑
+潸
+弘
+澶
+楹
+悲
+讫
+愤
+腥
+悸
+谍
+椹
+呢
+桓
+葭
+攫
+阀
+翰
+躲
+敖
+柑
+郎
+笨
+橇
+呃
+魁
+燎
+脓
+葩
+磋
+垛
+玺
+狮
+沓
+砜
+蕊
+锺
+罹
+蕉
+翱
+虐
+闾
+巫
+旦
+茱
+嬷
+枯
+鹏
+贡
+芹
+汛
+矫
+绁
+拣
+禺
+佃
+讣
+舫
+惯
+乳
+趋
+疲
+挽
+岚
+虾
+衾
+蠹
+蹂
+飓
+氦
+铖
+孩
+稞
+瑜
+壅
+掀
+勘
+妓
+畅
+髋
+W
+庐
+牲
+蓿
+榕
+练
+垣
+唱
+邸
+菲
+昆
+婺
+穿
+绡
+麒
+蚱
+掂
+愚
+泷
+涪
+漳
+妩
+娉
+榄
+讷
+觅
+旧
+藤
+煮
+呛
+柳
+腓
+叭
+庵
+烷
+阡
+罂
+蜕
+擂
+猖
+咿
+媲
+脉
+【
+沏
+貅
+黠
+熏
+哲
+烁
+坦
+酵
+兜
+×
+潇
+撒
+剽
+珩
+圹
+乾
+摸
+樟
+帽
+嗒
+襄
+魂
+轿
+憬
+锡
+〕
+喃
+皆
+咖
+隅
+脸
+残
+泮
+袂
+鹂
+珊
+囤
+捆
+咤
+误
+徨
+闹
+淙
+芊
+淋
+怆
+囗
+拨
+梳
+渤
+R
+G
+绨
+蚓
+婀
+幡
+狩
+麾
+谢
+唢
+裸
+旌
+伉
+纶
+裂
+驳
+砼
+咛
+澄
+樨
+蹈
+宙
+澍
+倍
+貔
+操
+勇
+蟠
+摈
+砧
+虬
+够
+缁
+悦
+藿
+撸
+艹
+摁
+淹
+豇
+虎
+榭
+ˉ
+吱
+d
+°
+喧
+荀
+踱
+侮
+奋
+偕
+饷
+犍
+惮
+坑
+璎
+徘
+宛
+妆
+袈
+倩
+窦
+昂
+荏
+乖
+K
+怅
+撰
+鳙
+牙
+袁
+酞
+X
+痿
+琼
+闸
+雁
+趾
+荚
+虻
+涝
+《
+杏
+韭
+偈
+烤
+绫
+鞘
+卉
+症
+遢
+蓥
+诋
+杭
+荨
+匆
+竣
+簪
+辙
+敕
+虞
+丹
+缭
+咩
+黟
+m
+淤
+瑕
+咂
+铉
+硼
+茨
+嶂
+痒
+畸
+敬
+涿
+粪
+窘
+熟
+叔
+嫔
+盾
+忱
+裘
+憾
+梵
+赡
+珙
+咯
+娘
+庙
+溯
+胺
+葱
+痪
+摊
+荷
+卞
+乒
+髦
+寐
+铭
+坩
+胗
+枷
+爆
+溟
+嚼
+羚
+砬
+轨
+惊
+挠
+罄
+竽
+菏
+氧
+浅
+楣
+盼
+枢
+炸
+阆
+杯
+谏
+噬
+淇
+渺
+俪
+秆
+墓
+泪
+跻
+砌
+痰
+垡
+渡
+耽
+釜
+讶
+鳎
+煞
+呗
+韶
+舶
+绷
+鹳
+缜
+旷
+铊
+皱
+龌
+檀
+霖
+奄
+槐
+艳
+蝶
+旋
+哝
+赶
+骞
+蚧
+腊
+盈
+丁
+`
+蜚
+矸
+蝙
+睨
+嚓
+僻
+鬼
+醴
+夜
+彝
+磊
+笔
+拔
+栀
+糕
+厦
+邰
+纫
+逭
+纤
+眦
+膊
+馍
+躇
+烯
+蘼
+冬
+诤
+暄
+骶
+哑
+瘠
+」
+臊
+丕
+愈
+咱
+螺
+擅
+跋
+搏
+硪
+谄
+笠
+淡
+嘿
+骅
+谧
+鼎
+皋
+姚
+歼
+蠢
+驼
+耳
+胬
+挝
+涯
+狗
+蒽
+孓
+犷
+凉
+芦
+箴
+铤
+孤
+嘛
+坤
+V
+茴
+朦
+挞
+尖
+橙
+诞
+搴
+碇
+洵
+浚
+帚
+蜍
+漯
+柘
+嚎
+讽
+芭
+荤
+咻
+祠
+秉
+跖
+埃
+吓
+糯
+眷
+馒
+惹
+娼
+鲑
+嫩
+讴
+轮
+瞥
+靶
+褚
+乏
+缤
+宋
+帧
+删
+驱
+碎
+扑
+俩
+俄
+偏
+涣
+竹
+噱
+皙
+佰
+渚
+唧
+斡
+#
+镉
+刀
+崎
+筐
+佣
+夭
+贰
+肴
+峙
+哔
+艿
+匐
+牺
+镛
+缘
+仡
+嫡
+劣
+枸
+堀
+梨
+簿
+鸭
+蒸
+亦
+稽
+浴
+{
+衢
+束
+槲
+j
+阁
+揍
+疥
+棋
+潋
+聪
+窜
+乓
+睛
+插
+冉
+阪
+苍
+搽
+「
+蟾
+螟
+幸
+仇
+樽
+撂
+慢
+跤
+幔
+俚
+淅
+覃
+觊
+溶
+妖
+帛
+侨
+曰
+妾
+泗
+·
+:
+瀘
+風
+Ë
+(
+)
+∶
+紅
+紗
+瑭
+雲
+頭
+鶏
+財
+許
+•
+¥
+樂
+焗
+麗
+—
+;
+滙
+東
+榮
+繪
+興
+…
+門
+業
+π
+楊
+國
+顧
+é
+盤
+寳
+Λ
+龍
+鳳
+島
+誌
+緣
+結
+銭
+萬
+勝
+祎
+璟
+優
+歡
+臨
+時
+購
+=
+★
+藍
+昇
+鐵
+觀
+勅
+農
+聲
+畫
+兿
+術
+發
+劉
+記
+專
+耑
+園
+書
+壴
+種
+Ο
+●
+褀
+號
+銀
+匯
+敟
+锘
+葉
+橪
+廣
+進
+蒄
+鑽
+阝
+祙
+貢
+鍋
+豊
+夬
+喆
+團
+閣
+開
+燁
+賓
+館
+酡
+沔
+順
++
+硚
+劵
+饸
+陽
+車
+湓
+復
+萊
+氣
+軒
+華
+堃
+迮
+纟
+戶
+馬
+學
+裡
+電
+嶽
+獨
+マ
+シ
+サ
+ジ
+燘
+袪
+環
+❤
+臺
+灣
+専
+賣
+孖
+聖
+攝
+線
+▪
+α
+傢
+俬
+夢
+達
+莊
+喬
+貝
+薩
+劍
+羅
+壓
+棛
+饦
+尃
+璈
+囍
+醫
+G
+I
+A
+#
+N
+鷄
+髙
+嬰
+啓
+約
+隹
+潔
+賴
+藝
+~
+寶
+籣
+麺
+
+嶺
+√
+義
+網
+峩
+長
+∧
+魚
+機
+構
+②
+鳯
+偉
+L
+B
+㙟
+畵
+鴿
+'
+詩
+溝
+嚞
+屌
+藔
+佧
+玥
+蘭
+織
+1
+3
+9
+0
+7
+點
+砭
+鴨
+鋪
+銘
+廳
+弍
+‧
+創
+湯
+坶
+℃
+卩
+骝
+&
+烜
+荘
+當
+潤
+扞
+係
+懷
+碶
+钅
+蚨
+讠
+☆
+叢
+爲
+埗
+涫
+塗
+→
+楽
+現
+鯨
+愛
+瑪
+鈺
+忄
+悶
+藥
+飾
+樓
+視
+孬
+ㆍ
+燚
+苪
+師
+①
+丼
+锽
+│
+韓
+標
+è
+兒
+閏
+匋
+張
+漢
+Ü
+髪
+會
+閑
+檔
+習
+裝
+の
+峯
+菘
+輝
+И
+雞
+釣
+億
+浐
+K
+O
+R
+8
+H
+E
+P
+T
+W
+D
+S
+C
+M
+F
+姌
+饹
+»
+晞
+廰
+ä
+嵯
+鷹
+負
+飲
+絲
+冚
+楗
+澤
+綫
+區
+❋
+←
+質
+靑
+揚
+③
+滬
+統
+産
+協
+﹑
+乸
+畐
+經
+運
+際
+洺
+岽
+為
+粵
+諾
+崋
+豐
+碁
+ɔ
+V
+2
+6
+齋
+誠
+訂
+´
+勑
+雙
+陳
+無
+í
+泩
+媄
+夌
+刂
+i
+c
+t
+o
+r
+a
+嘢
+耄
+燴
+暃
+壽
+媽
+靈
+抻
+體
+唻
+É
+冮
+甹
+鎮
+錦
+ʌ
+蜛
+蠄
+尓
+駕
+戀
+飬
+逹
+倫
+貴
+極
+Я
+Й
+寬
+磚
+嶪
+郎
+職
+|
+間
+n
+d
+剎
+伈
+課
+飛
+橋
+瘊
+№
+譜
+骓
+圗
+滘
+縣
+粿
+咅
+養
+濤
+彳
+®
+%
+Ⅱ
+啰
+㴪
+見
+矞
+薬
+糁
+邨
+鲮
+顔
+罱
+З
+選
+話
+贏
+氪
+俵
+競
+瑩
+繡
+枱
+β
+綉
+á
+獅
+爾
+™
+麵
+戋
+淩
+徳
+個
+劇
+場
+務
+簡
+寵
+h
+實
+膠
+轱
+圖
+築
+嘣
+樹
+㸃
+營
+耵
+孫
+饃
+鄺
+飯
+麯
+遠
+輸
+坫
+孃
+乚
+閃
+鏢
+㎡
+題
+廠
+關
+↑
+爺
+將
+軍
+連
+篦
+覌
+參
+箸
+-
+窠
+棽
+寕
+夀
+爰
+歐
+呙
+閥
+頡
+熱
+雎
+垟
+裟
+凬
+勁
+帑
+馕
+夆
+疌
+枼
+馮
+貨
+蒤
+樸
+彧
+旸
+靜
+龢
+暢
+㐱
+鳥
+珺
+鏡
+灡
+爭
+堷
+廚
+Ó
+騰
+診
+┅
+蘇
+褔
+凱
+頂
+豕
+亞
+帥
+嘬
+⊥
+仺
+桖
+複
+饣
+絡
+穂
+顏
+棟
+納
+▏
+濟
+親
+設
+計
+攵
+埌
+烺
+ò
+頤
+燦
+蓮
+撻
+節
+講
+濱
+濃
+娽
+洳
+朿
+燈
+鈴
+護
+膚
+铔
+過
+補
+Z
+U
+5
+4
+坋
+闿
+䖝
+餘
+缐
+铞
+貿
+铪
+桼
+趙
+鍊
+[
+㐂
+垚
+菓
+揸
+捲
+鐘
+滏
+𣇉
+爍
+輪
+燜
+鴻
+鮮
+動
+鹞
+鷗
+丄
+慶
+鉌
+翥
+飮
+腸
+⇋
+漁
+覺
+來
+熘
+昴
+翏
+鲱
+圧
+鄉
+萭
+頔
+爐
+嫚
+г
+貭
+類
+聯
+幛
+輕
+訓
+鑒
+夋
+锨
+芃
+珣
+䝉
+扙
+嵐
+銷
+處
+ㄱ
+語
+誘
+苝
+歸
+儀
+燒
+楿
+內
+粢
+葒
+奧
+麥
+礻
+滿
+蠔
+穵
+瞭
+態
+鱬
+榞
+硂
+鄭
+黃
+煙
+祐
+奓
+逺
+*
+瑄
+獲
+聞
+薦
+讀
+這
+樣
+決
+問
+啟
+們
+執
+説
+轉
+單
+隨
+唘
+帶
+倉
+庫
+還
+贈
+尙
+皺
+■
+餅
+產
+○
+∈
+報
+狀
+楓
+賠
+琯
+嗮
+禮
+`
+傳
+>
+≤
+嗞
+Φ
+≥
+換
+咭
+∣
+↓
+曬
+ε
+応
+寫
+″
+終
+様
+純
+費
+療
+聨
+凍
+壐
+郵
+ü
+黒
+∫
+製
+塊
+調
+軽
+確
+撃
+級
+馴
+Ⅲ
+涇
+繹
+數
+碼
+證
+狒
+処
+劑
+<
+晧
+賀
+衆
+]
+櫥
+兩
+陰
+絶
+對
+鯉
+憶
+◎
+p
+e
+Y
+蕒
+煖
+頓
+測
+試
+鼽
+僑
+碩
+妝
+帯
+≈
+鐡
+舖
+權
+喫
+倆
+ˋ
+該
+悅
+ā
+俫
+.
+f
+s
+b
+m
+k
+g
+u
+j
+貼
+淨
+濕
+針
+適
+備
+l
+/
+給
+謢
+強
+觸
+衛
+與
+⊙
+$
+緯
+變
+⑴
+⑵
+⑶
+㎏
+殺
+∩
+幚
+─
+價
+▲
+離
+ú
+ó
+飄
+烏
+関
+閟
+﹝
+﹞
+邏
+輯
+鍵
+驗
+訣
+導
+歷
+屆
+層
+▼
+儱
+錄
+熳
+ē
+艦
+吋
+錶
+辧
+飼
+顯
+④
+禦
+販
+気
+対
+枰
+閩
+紀
+幹
+瞓
+貊
+淚
+△
+眞
+墊
+Ω
+獻
+褲
+縫
+緑
+亜
+鉅
+餠
+{
+}
+◆
+蘆
+薈
+█
+◇
+溫
+彈
+晳
+粧
+犸
+穩
+訊
+崬
+凖
+熥
+П
+舊
+條
+紋
+圍
+Ⅳ
+筆
+尷
+難
+雜
+錯
+綁
+識
+頰
+鎖
+艶
+□
+殁
+殼
+⑧
+├
+▕
+鵬
+ǐ
+ō
+ǒ
+糝
+綱
+▎
+μ
+盜
+饅
+醬
+籤
+蓋
+釀
+鹽
+據
+à
+ɡ
+辦
+◥
+彐
+┌
+婦
+獸
+鲩
+伱
+ī
+蒟
+蒻
+齊
+袆
+腦
+寧
+凈
+妳
+煥
+詢
+偽
+謹
+啫
+鯽
+騷
+鱸
+損
+傷
+鎻
+髮
+買
+冏
+儥
+両
+﹢
+∞
+載
+喰
+z
+羙
+悵
+燙
+曉
+員
+組
+徹
+艷
+痠
+鋼
+鼙
+縮
+細
+嚒
+爯
+≠
+維
+"
+鱻
+壇
+厍
+帰
+浥
+犇
+薡
+軎
+²
+應
+醜
+刪
+緻
+鶴
+賜
+噁
+軌
+尨
+镔
+鷺
+槗
+彌
+葚
+濛
+請
+溇
+緹
+賢
+訪
+獴
+瑅
+資
+縤
+陣
+蕟
+栢
+韻
+祼
+恁
+伢
+謝
+劃
+涑
+總
+衖
+踺
+砋
+凉
+籃
+駿
+苼
+瘋
+昽
+紡
+驊
+腎
+﹗
+響
+杋
+剛
+嚴
+禪
+歓
+槍
+傘
+檸
+檫
+炣
+勢
+鏜
+鎢
+銑
+尐
+減
+奪
+惡
+θ
+僮
+婭
+臘
+ū
+ì
+殻
+鉄
+∑
+蛲
+焼
+緖
+續
+紹
+懮
\ No newline at end of file
diff --git a/ocr-studio/PaddleOCR/ppocr/utils/profiler.py b/ocr-studio/PaddleOCR/ppocr/utils/profiler.py
new file mode 100644
index 0000000000000000000000000000000000000000..629ef4ef054a050afd1bc0ce819cb664b9503e9f
--- /dev/null
+++ b/ocr-studio/PaddleOCR/ppocr/utils/profiler.py
@@ -0,0 +1,128 @@
+# copyright (c) 2021 PaddlePaddle Authors. All Rights Reserve.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import sys
+import paddle.profiler as profiler
+
+# A global variable to record the number of calling times for profiler
+# functions. It is used to specify the tracing range of training steps.
+_profiler_step_id = 0
+
+# A global variable to avoid parsing from string every time.
+_profiler_options = None
+_prof = None
+
+class ProfilerOptions(object):
+ '''
+ Use a string to initialize a ProfilerOptions.
+ The string should be in the format: "key1=value1;key2=value;key3=value3".
+ For example:
+ "profile_path=model.profile"
+ "batch_range=[50, 60]; profile_path=model.profile"
+ "batch_range=[50, 60]; tracer_option=OpDetail; profile_path=model.profile"
+
+ ProfilerOptions supports following key-value pair:
+ batch_range - a integer list, e.g. [100, 110].
+ state - a string, the optional values are 'CPU', 'GPU' or 'All'.
+ sorted_key - a string, the optional values are 'calls', 'total',
+ 'max', 'min' or 'ave.
+ tracer_option - a string, the optional values are 'Default', 'OpDetail',
+ 'AllOpDetail'.
+ profile_path - a string, the path to save the serialized profile data,
+ which can be used to generate a timeline.
+ exit_on_finished - a boolean.
+ '''
+
+ def __init__(self, options_str):
+ assert isinstance(options_str, str)
+
+ self._options = {
+ 'batch_range': [10, 20],
+ 'state': 'All',
+ 'sorted_key': 'total',
+ 'tracer_option': 'Default',
+ 'profile_path': '/tmp/profile',
+ 'exit_on_finished': True,
+ 'timer_only': True
+ }
+ self._parse_from_string(options_str)
+
+ def _parse_from_string(self, options_str):
+ for kv in options_str.replace(' ', '').split(';'):
+ key, value = kv.split('=')
+ if key == 'batch_range':
+ value_list = value.replace('[', '').replace(']', '').split(',')
+ value_list = list(map(int, value_list))
+ if len(value_list) >= 2 and value_list[0] >= 0 and value_list[
+ 1] > value_list[0]:
+ self._options[key] = value_list
+ elif key == 'exit_on_finished':
+ self._options[key] = value.lower() in ("yes", "true", "t", "1")
+ elif key in [
+ 'state', 'sorted_key', 'tracer_option', 'profile_path'
+ ]:
+ self._options[key] = value
+ elif key == 'timer_only':
+ self._options[key] = value
+
+ def __getitem__(self, name):
+ if self._options.get(name, None) is None:
+ raise ValueError(
+ "ProfilerOptions does not have an option named %s." % name)
+ return self._options[name]
+
+
+def add_profiler_step(options_str=None):
+ '''
+ Enable the operator-level timing using PaddlePaddle's profiler.
+ The profiler uses a independent variable to count the profiler steps.
+ One call of this function is treated as a profiler step.
+ Args:
+ profiler_options - a string to initialize the ProfilerOptions.
+ Default is None, and the profiler is disabled.
+ '''
+ if options_str is None:
+ return
+
+ global _prof
+ global _profiler_step_id
+ global _profiler_options
+
+ if _profiler_options is None:
+ _profiler_options = ProfilerOptions(options_str)
+ # profile : https://www.paddlepaddle.org.cn/documentation/docs/zh/guides/performance_improving/profiling_model.html#chakanxingnengshujudetongjibiaodan
+ # timer_only = True only the model's throughput and time overhead are displayed
+ # timer_only = False calling summary can print a statistical form that presents performance data from different perspectives.
+ # timer_only = False the output Timeline information can be found in the profiler_log directory
+ if _prof is None:
+ _timer_only = str(_profiler_options['timer_only']) == str(True)
+ _prof = profiler.Profiler(
+ scheduler = (_profiler_options['batch_range'][0], _profiler_options['batch_range'][1]),
+ on_trace_ready = profiler.export_chrome_tracing('./profiler_log'),
+ timer_only = _timer_only)
+ _prof.start()
+ else:
+ _prof.step()
+
+ if _profiler_step_id == _profiler_options['batch_range'][1]:
+ _prof.stop()
+ _prof.summary(
+ op_detail=True,
+ thread_sep=False,
+ time_unit='ms')
+ _prof = None
+ if _profiler_options['exit_on_finished']:
+ sys.exit(0)
+
+ _profiler_step_id += 1
diff --git a/ocr-studio/PaddleOCR/ppocr/utils/save_load.py b/ocr-studio/PaddleOCR/ppocr/utils/save_load.py
new file mode 100644
index 0000000000000000000000000000000000000000..e6a81c48dfd43245f13f69e1a5679d08838ca603
--- /dev/null
+++ b/ocr-studio/PaddleOCR/ppocr/utils/save_load.py
@@ -0,0 +1,239 @@
+# Copyright (c) 2020 PaddlePaddle Authors. All Rights Reserve.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+from __future__ import absolute_import
+from __future__ import division
+from __future__ import print_function
+
+import errno
+import os
+import pickle
+import six
+
+import paddle
+
+from ppocr.utils.logging import get_logger
+from ppocr.utils.network import maybe_download_params
+
+__all__ = ['load_model']
+
+
+def _mkdir_if_not_exist(path, logger):
+ """
+ mkdir if not exists, ignore the exception when multiprocess mkdir together
+ """
+ if not os.path.exists(path):
+ try:
+ os.makedirs(path)
+ except OSError as e:
+ if e.errno == errno.EEXIST and os.path.isdir(path):
+ logger.warning(
+ 'be happy if some process has already created {}'.format(
+ path))
+ else:
+ raise OSError('Failed to mkdir {}'.format(path))
+
+
+def load_model(config, model, optimizer=None, model_type='det'):
+ """
+ load model from checkpoint or pretrained_model
+ """
+ logger = get_logger()
+ global_config = config['Global']
+ checkpoints = global_config.get('checkpoints')
+ pretrained_model = global_config.get('pretrained_model')
+ best_model_dict = {}
+ is_float16 = False
+ is_nlp_model = model_type == 'kie' and config["Architecture"][
+ "algorithm"] not in ["SDMGR"]
+
+ if is_nlp_model is True:
+ # NOTE: for kie model dsitillation, resume training is not supported now
+ if config["Architecture"]["algorithm"] in ["Distillation"]:
+ return best_model_dict
+ checkpoints = config['Architecture']['Backbone']['checkpoints']
+ # load kie method metric
+ if checkpoints:
+ if os.path.exists(os.path.join(checkpoints, 'metric.states')):
+ with open(os.path.join(checkpoints, 'metric.states'),
+ 'rb') as f:
+ states_dict = pickle.load(f) if six.PY2 else pickle.load(
+ f, encoding='latin1')
+ best_model_dict = states_dict.get('best_model_dict', {})
+ if 'epoch' in states_dict:
+ best_model_dict['start_epoch'] = states_dict['epoch'] + 1
+ logger.info("resume from {}".format(checkpoints))
+
+ if optimizer is not None:
+ if checkpoints[-1] in ['/', '\\']:
+ checkpoints = checkpoints[:-1]
+ if os.path.exists(checkpoints + '.pdopt'):
+ optim_dict = paddle.load(checkpoints + '.pdopt')
+ optimizer.set_state_dict(optim_dict)
+ else:
+ logger.warning(
+ "{}.pdopt is not exists, params of optimizer is not loaded".
+ format(checkpoints))
+
+ return best_model_dict
+
+ if checkpoints:
+ if checkpoints.endswith('.pdparams'):
+ checkpoints = checkpoints.replace('.pdparams', '')
+ assert os.path.exists(checkpoints + ".pdparams"), \
+ "The {}.pdparams does not exists!".format(checkpoints)
+
+ # load params from trained model
+ params = paddle.load(checkpoints + '.pdparams')
+ state_dict = model.state_dict()
+ new_state_dict = {}
+ for key, value in state_dict.items():
+ if key not in params:
+ logger.warning("{} not in loaded params {} !".format(
+ key, params.keys()))
+ continue
+ pre_value = params[key]
+ if pre_value.dtype == paddle.float16:
+ is_float16 = True
+ if pre_value.dtype != value.dtype:
+ pre_value = pre_value.astype(value.dtype)
+ if list(value.shape) == list(pre_value.shape):
+ new_state_dict[key] = pre_value
+ else:
+ logger.warning(
+ "The shape of model params {} {} not matched with loaded params shape {} !".
+ format(key, value.shape, pre_value.shape))
+ model.set_state_dict(new_state_dict)
+ if is_float16:
+ logger.info(
+ "The parameter type is float16, which is converted to float32 when loading"
+ )
+ if optimizer is not None:
+ if os.path.exists(checkpoints + '.pdopt'):
+ optim_dict = paddle.load(checkpoints + '.pdopt')
+ optimizer.set_state_dict(optim_dict)
+ else:
+ logger.warning(
+ "{}.pdopt is not exists, params of optimizer is not loaded".
+ format(checkpoints))
+
+ if os.path.exists(checkpoints + '.states'):
+ with open(checkpoints + '.states', 'rb') as f:
+ states_dict = pickle.load(f) if six.PY2 else pickle.load(
+ f, encoding='latin1')
+ best_model_dict = states_dict.get('best_model_dict', {})
+ if 'epoch' in states_dict:
+ best_model_dict['start_epoch'] = states_dict['epoch'] + 1
+ logger.info("resume from {}".format(checkpoints))
+ elif pretrained_model:
+ is_float16 = load_pretrained_params(model, pretrained_model)
+ else:
+ logger.info('train from scratch')
+ best_model_dict['is_float16'] = is_float16
+ return best_model_dict
+
+
+def load_pretrained_params(model, path):
+ logger = get_logger()
+ path = maybe_download_params(path)
+ if path.endswith('.pdparams'):
+ path = path.replace('.pdparams', '')
+ assert os.path.exists(path + ".pdparams"), \
+ "The {}.pdparams does not exists!".format(path)
+
+ params = paddle.load(path + '.pdparams')
+
+ state_dict = model.state_dict()
+
+ new_state_dict = {}
+ is_float16 = False
+
+ for k1 in params.keys():
+
+ if k1 not in state_dict.keys():
+ logger.warning("The pretrained params {} not in model".format(k1))
+ else:
+ if params[k1].dtype == paddle.float16:
+ is_float16 = True
+ if params[k1].dtype != state_dict[k1].dtype:
+ params[k1] = params[k1].astype(state_dict[k1].dtype)
+ if list(state_dict[k1].shape) == list(params[k1].shape):
+ new_state_dict[k1] = params[k1]
+ else:
+ logger.warning(
+ "The shape of model params {} {} not matched with loaded params {} {} !".
+ format(k1, state_dict[k1].shape, k1, params[k1].shape))
+
+ model.set_state_dict(new_state_dict)
+ if is_float16:
+ logger.info(
+ "The parameter type is float16, which is converted to float32 when loading"
+ )
+ logger.info("load pretrain successful from {}".format(path))
+ return is_float16
+
+
+def save_model(model,
+ optimizer,
+ model_path,
+ logger,
+ config,
+ is_best=False,
+ prefix='ppocr',
+ **kwargs):
+ """
+ save model to the target path
+ """
+ _mkdir_if_not_exist(model_path, logger)
+ model_prefix = os.path.join(model_path, prefix)
+
+ if prefix == 'best_accuracy':
+ best_model_path = os.path.join(model_path, 'best_model')
+ _mkdir_if_not_exist(best_model_path, logger)
+
+ paddle.save(optimizer.state_dict(), model_prefix + '.pdopt')
+ if prefix == 'best_accuracy':
+ paddle.save(optimizer.state_dict(),
+ os.path.join(best_model_path, 'model.pdopt'))
+
+ is_nlp_model = config['Architecture']["model_type"] == 'kie' and config[
+ "Architecture"]["algorithm"] not in ["SDMGR"]
+ if is_nlp_model is not True:
+ paddle.save(model.state_dict(), model_prefix + '.pdparams')
+ metric_prefix = model_prefix
+
+ if prefix == 'best_accuracy':
+ paddle.save(model.state_dict(),
+ os.path.join(best_model_path, 'model.pdparams'))
+
+ else: # for kie system, we follow the save/load rules in NLP
+ if config['Global']['distributed']:
+ arch = model._layers
+ else:
+ arch = model
+ if config["Architecture"]["algorithm"] in ["Distillation"]:
+ arch = arch.Student
+ arch.backbone.model.save_pretrained(model_prefix)
+ metric_prefix = os.path.join(model_prefix, 'metric')
+
+ if prefix == 'best_accuracy':
+ arch.backbone.model.save_pretrained(best_model_path)
+
+ # save metric and config
+ with open(metric_prefix + '.states', 'wb') as f:
+ pickle.dump(kwargs, f, protocol=2)
+ if is_best:
+ logger.info('save best model is to {}'.format(model_prefix))
+ else:
+ logger.info("save model in {}".format(model_prefix))
diff --git a/ocr-studio/PaddleOCR/ppocr/utils/stats.py b/ocr-studio/PaddleOCR/ppocr/utils/stats.py
new file mode 100644
index 0000000000000000000000000000000000000000..179b0082f16133ac202c6f0dc120ec07c10fd18e
--- /dev/null
+++ b/ocr-studio/PaddleOCR/ppocr/utils/stats.py
@@ -0,0 +1,72 @@
+# Copyright (c) 2020 PaddlePaddle Authors. All Rights Reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import collections
+import numpy as np
+import datetime
+
+__all__ = ['TrainingStats', 'Time']
+
+
+class SmoothedValue(object):
+ """Track a series of values and provide access to smoothed values over a
+ window or the global series average.
+ """
+
+ def __init__(self, window_size):
+ self.deque = collections.deque(maxlen=window_size)
+
+ def add_value(self, value):
+ self.deque.append(value)
+
+ def get_median_value(self):
+ return np.median(self.deque)
+
+
+def Time():
+ return datetime.datetime.now().strftime('%Y-%m-%d %H:%M:%S.%f')
+
+
+class TrainingStats(object):
+ def __init__(self, window_size, stats_keys):
+ self.window_size = window_size
+ self.smoothed_losses_and_metrics = {
+ key: SmoothedValue(window_size)
+ for key in stats_keys
+ }
+
+ def update(self, stats):
+ for k, v in stats.items():
+ if k not in self.smoothed_losses_and_metrics:
+ self.smoothed_losses_and_metrics[k] = SmoothedValue(
+ self.window_size)
+ self.smoothed_losses_and_metrics[k].add_value(v)
+
+ def get(self, extras=None):
+ stats = collections.OrderedDict()
+ if extras:
+ for k, v in extras.items():
+ stats[k] = v
+ for k, v in self.smoothed_losses_and_metrics.items():
+ stats[k] = round(v.get_median_value(), 6)
+
+ return stats
+
+ def log(self, extras=None):
+ d = self.get(extras)
+ strs = []
+ for k, v in d.items():
+ strs.append('{}: {:x<6f}'.format(k, v))
+ strs = ', '.join(strs)
+ return strs
diff --git a/ocr-studio/PaddleOCR/ppocr/utils/utility.py b/ocr-studio/PaddleOCR/ppocr/utils/utility.py
new file mode 100644
index 0000000000000000000000000000000000000000..6c25ba25d7b96232efa04abbd09033e67b6f779e
--- /dev/null
+++ b/ocr-studio/PaddleOCR/ppocr/utils/utility.py
@@ -0,0 +1,192 @@
+# Copyright (c) 2020 PaddlePaddle Authors. All Rights Reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import logging
+import os
+import cv2
+import random
+import numpy as np
+import paddle
+import importlib.util
+import sys
+import subprocess
+
+
+def print_dict(d, logger, delimiter=0):
+ """
+ Recursively visualize a dict and
+ indenting acrrording by the relationship of keys.
+ """
+ for k, v in sorted(d.items()):
+ if isinstance(v, dict):
+ logger.info("{}{} : ".format(delimiter * " ", str(k)))
+ print_dict(v, logger, delimiter + 4)
+ elif isinstance(v, list) and len(v) >= 1 and isinstance(v[0], dict):
+ logger.info("{}{} : ".format(delimiter * " ", str(k)))
+ for value in v:
+ print_dict(value, logger, delimiter + 4)
+ else:
+ logger.info("{}{} : {}".format(delimiter * " ", k, v))
+
+
+def get_check_global_params(mode):
+ check_params = ['use_gpu', 'max_text_length', 'image_shape', \
+ 'image_shape', 'character_type', 'loss_type']
+ if mode == "train_eval":
+ check_params = check_params + [ \
+ 'train_batch_size_per_card', 'test_batch_size_per_card']
+ elif mode == "test":
+ check_params = check_params + ['test_batch_size_per_card']
+ return check_params
+
+
+def _check_image_file(path):
+ img_end = {'jpg', 'bmp', 'png', 'jpeg', 'rgb', 'tif', 'tiff', 'gif', 'pdf'}
+ return any([path.lower().endswith(e) for e in img_end])
+
+
+def get_image_file_list(img_file, infer_list=None):
+ imgs_lists = []
+ if img_file is None or not os.path.exists(img_file):
+ raise Exception("not found any img file in {}".format(img_file))
+
+ if os.path.isfile(img_file) and _check_image_file(img_file):
+ imgs_lists.append(img_file)
+ elif os.path.isdir(img_file):
+ for single_file in os.listdir(img_file):
+ file_path = os.path.join(img_file, single_file)
+ if os.path.isfile(file_path) and _check_image_file(file_path):
+ imgs_lists.append(file_path)
+
+ if len(imgs_lists) == 0:
+ raise Exception("not found any img file in {}".format(img_file))
+ imgs_lists = sorted(imgs_lists)
+ return imgs_lists
+
+def binarize_img(img):
+ if len(img.shape) == 3 and img.shape[2] == 3:
+ gray = cv2.cvtColor(img, cv2.COLOR_BGR2GRAY) # conversion to grayscale image
+ # use cv2 threshold binarization
+ _, gray = cv2.threshold(gray, 0, 255, cv2.THRESH_BINARY + cv2.THRESH_OTSU)
+ img = cv2.cvtColor(gray, cv2.COLOR_GRAY2BGR)
+ return img
+
+def alpha_to_color(img, alpha_color=(255, 255, 255)):
+ if len(img.shape) == 3 and img.shape[2] == 4:
+ B, G, R, A = cv2.split(img)
+ alpha = A / 255
+
+ R = (alpha_color[0] * (1 - alpha) + R * alpha).astype(np.uint8)
+ G = (alpha_color[1] * (1 - alpha) + G * alpha).astype(np.uint8)
+ B = (alpha_color[2] * (1 - alpha) + B * alpha).astype(np.uint8)
+
+ img = cv2.merge((B, G, R))
+ return img
+
+def check_and_read(img_path):
+ if os.path.basename(img_path)[-3:].lower() == 'gif':
+ gif = cv2.VideoCapture(img_path)
+ ret, frame = gif.read()
+ if not ret:
+ logger = logging.getLogger('ppocr')
+ logger.info("Cannot read {}. This gif image maybe corrupted.")
+ return None, False
+ if len(frame.shape) == 2 or frame.shape[-1] == 1:
+ frame = cv2.cvtColor(frame, cv2.COLOR_GRAY2RGB)
+ imgvalue = frame[:, :, ::-1]
+ return imgvalue, True, False
+ elif os.path.basename(img_path)[-3:].lower() == 'pdf':
+ from paddle.utils import try_import
+ fitz = try_import("fitz")
+ from PIL import Image
+ imgs = []
+ with fitz.open(img_path) as pdf:
+ for pg in range(0, pdf.page_count):
+ page = pdf[pg]
+ mat = fitz.Matrix(2, 2)
+ pm = page.get_pixmap(matrix=mat, alpha=False)
+
+ # if width or height > 2000 pixels, don't enlarge the image
+ if pm.width > 2000 or pm.height > 2000:
+ pm = page.get_pixmap(matrix=fitz.Matrix(1, 1), alpha=False)
+
+ img = Image.frombytes("RGB", [pm.width, pm.height], pm.samples)
+ img = cv2.cvtColor(np.array(img), cv2.COLOR_RGB2BGR)
+ imgs.append(img)
+ return imgs, False, True
+ return None, False, False
+
+
+def load_vqa_bio_label_maps(label_map_path):
+ with open(label_map_path, "r", encoding='utf-8') as fin:
+ lines = fin.readlines()
+ old_lines = [line.strip() for line in lines]
+ lines = ["O"]
+ for line in old_lines:
+ # "O" has already been in lines
+ if line.upper() in ["OTHER", "OTHERS", "IGNORE"]:
+ continue
+ lines.append(line)
+ labels = ["O"]
+ for line in lines[1:]:
+ labels.append("B-" + line)
+ labels.append("I-" + line)
+ label2id_map = {label.upper(): idx for idx, label in enumerate(labels)}
+ id2label_map = {idx: label.upper() for idx, label in enumerate(labels)}
+ return label2id_map, id2label_map
+
+
+def set_seed(seed=1024):
+ random.seed(seed)
+ np.random.seed(seed)
+ paddle.seed(seed)
+
+
+def check_install(module_name, install_name):
+ spec = importlib.util.find_spec(module_name)
+ if spec is None:
+ print(f'Warnning! The {module_name} module is NOT installed')
+ print(
+ f'Try install {module_name} module automatically. You can also try to install manually by pip install {install_name}.'
+ )
+ python = sys.executable
+ try:
+ subprocess.check_call(
+ [python, '-m', 'pip', 'install', install_name],
+ stdout=subprocess.DEVNULL)
+ print(f'The {module_name} module is now installed')
+ except subprocess.CalledProcessError as exc:
+ raise Exception(
+ f"Install {module_name} failed, please install manually")
+ else:
+ print(f"{module_name} has been installed.")
+
+
+class AverageMeter:
+ def __init__(self):
+ self.reset()
+
+ def reset(self):
+ """reset"""
+ self.val = 0
+ self.avg = 0
+ self.sum = 0
+ self.count = 0
+
+ def update(self, val, n=1):
+ """update"""
+ self.val = val
+ self.sum += val * n
+ self.count += n
+ self.avg = self.sum / self.count
diff --git a/ocr-studio/PaddleOCR/ppocr/utils/visual.py b/ocr-studio/PaddleOCR/ppocr/utils/visual.py
new file mode 100644
index 0000000000000000000000000000000000000000..9108a3728143e0ef0a0d6705e4cc701ab9588394
--- /dev/null
+++ b/ocr-studio/PaddleOCR/ppocr/utils/visual.py
@@ -0,0 +1,131 @@
+# copyright (c) 2021 PaddlePaddle Authors. All Rights Reserve.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+import cv2
+import os
+import numpy as np
+import PIL
+from PIL import Image, ImageDraw, ImageFont
+
+
+def draw_ser_results(image,
+ ocr_results,
+ font_path="doc/fonts/simfang.ttf",
+ font_size=14):
+ np.random.seed(2021)
+ color = (np.random.permutation(range(255)),
+ np.random.permutation(range(255)),
+ np.random.permutation(range(255)))
+ color_map = {
+ idx: (color[0][idx], color[1][idx], color[2][idx])
+ for idx in range(1, 255)
+ }
+ if isinstance(image, np.ndarray):
+ image = Image.fromarray(image)
+ elif isinstance(image, str) and os.path.isfile(image):
+ image = Image.open(image).convert('RGB')
+ img_new = image.copy()
+ draw = ImageDraw.Draw(img_new)
+
+ font = ImageFont.truetype(font_path, font_size, encoding="utf-8")
+ for ocr_info in ocr_results:
+ if ocr_info["pred_id"] not in color_map:
+ continue
+ color = color_map[ocr_info["pred_id"]]
+ text = "{}: {}".format(ocr_info["pred"], ocr_info["transcription"])
+
+ if "bbox" in ocr_info:
+ # draw with ocr engine
+ bbox = ocr_info["bbox"]
+ else:
+ # draw with ocr groundtruth
+ bbox = trans_poly_to_bbox(ocr_info["points"])
+ draw_box_txt(bbox, text, draw, font, font_size, color)
+
+ img_new = Image.blend(image, img_new, 0.7)
+ return np.array(img_new)
+
+
+def draw_box_txt(bbox, text, draw, font, font_size, color):
+
+ # draw ocr results outline
+ bbox = ((bbox[0], bbox[1]), (bbox[2], bbox[3]))
+ draw.rectangle(bbox, fill=color)
+
+ # draw ocr results
+ if int(PIL.__version__.split('.')[0]) < 10:
+ tw = font.getsize(text)[0]
+ th = font.getsize(text)[1]
+ else:
+ left, top, right, bottom = font.getbbox(text)
+ tw, th = right - left, bottom - top
+
+ start_y = max(0, bbox[0][1] - th)
+ draw.rectangle(
+ [(bbox[0][0] + 1, start_y), (bbox[0][0] + tw + 1, start_y + th)],
+ fill=(0, 0, 255))
+ draw.text((bbox[0][0] + 1, start_y), text, fill=(255, 255, 255), font=font)
+
+
+def trans_poly_to_bbox(poly):
+ x1 = np.min([p[0] for p in poly])
+ x2 = np.max([p[0] for p in poly])
+ y1 = np.min([p[1] for p in poly])
+ y2 = np.max([p[1] for p in poly])
+ return [x1, y1, x2, y2]
+
+
+def draw_re_results(image,
+ result,
+ font_path="doc/fonts/simfang.ttf",
+ font_size=18):
+ np.random.seed(0)
+ if isinstance(image, np.ndarray):
+ image = Image.fromarray(image)
+ elif isinstance(image, str) and os.path.isfile(image):
+ image = Image.open(image).convert('RGB')
+ img_new = image.copy()
+ draw = ImageDraw.Draw(img_new)
+
+ font = ImageFont.truetype(font_path, font_size, encoding="utf-8")
+ color_head = (0, 0, 255)
+ color_tail = (255, 0, 0)
+ color_line = (0, 255, 0)
+
+ for ocr_info_head, ocr_info_tail in result:
+ draw_box_txt(ocr_info_head["bbox"], ocr_info_head["transcription"],
+ draw, font, font_size, color_head)
+ draw_box_txt(ocr_info_tail["bbox"], ocr_info_tail["transcription"],
+ draw, font, font_size, color_tail)
+
+ center_head = (
+ (ocr_info_head['bbox'][0] + ocr_info_head['bbox'][2]) // 2,
+ (ocr_info_head['bbox'][1] + ocr_info_head['bbox'][3]) // 2)
+ center_tail = (
+ (ocr_info_tail['bbox'][0] + ocr_info_tail['bbox'][2]) // 2,
+ (ocr_info_tail['bbox'][1] + ocr_info_tail['bbox'][3]) // 2)
+
+ draw.line([center_head, center_tail], fill=color_line, width=5)
+
+ img_new = Image.blend(image, img_new, 0.5)
+ return np.array(img_new)
+
+
+def draw_rectangle(img_path, boxes):
+ boxes = np.array(boxes)
+ img = cv2.imread(img_path)
+ img_show = img.copy()
+ for box in boxes.astype(int):
+ x1, y1, x2, y2 = box
+ cv2.rectangle(img_show, (x1, y1), (x2, y2), (255, 0, 0), 2)
+ return img_show
\ No newline at end of file
diff --git a/ocr-studio/PaddleOCR/pyproject.toml b/ocr-studio/PaddleOCR/pyproject.toml
new file mode 100644
index 0000000000000000000000000000000000000000..68c0b31582a1cb82bb21e92a2b2592927e851a9d
--- /dev/null
+++ b/ocr-studio/PaddleOCR/pyproject.toml
@@ -0,0 +1,87 @@
+[build-system]
+requires = ["setuptools==72.1.0", "wheel", "setuptools_scm"]
+build-backend = "setuptools.build_meta"
+
+[project]
+name = "paddleocr"
+# After each version release, the version number needs to be incremented
+dynamic = ["version"]
+description = "Awesome multilingual OCR and document parsing toolkits based on PaddlePaddle"
+authors = [
+ {name = "PaddlePaddle", email = "paddleocr@baidu.com"},
+]
+maintainers = [
+ {name = "PaddlePaddle", email = "paddleocr@baidu.com"},
+]
+readme = "README.md"
+requires-python = ">=3.8"
+keywords = [
+ "ocr",
+ "textdetection",
+ "textrecognition",
+ "paddleocr",
+ "chineseocr",
+ "pp-ocr",
+ "pp-structure",
+ "document-parsing",
+ "pdf2markdown",
+ "doc2markdown",
+ "docx2markdown",
+ "kie",
+ "pp-chatocr",
+ "document-translation",
+ "rag"
+]
+license = {text = "Apache License 2.0"}
+classifiers = [
+ "Intended Audience :: Developers",
+ "Operating System :: OS Independent",
+ "Natural Language :: Chinese (Simplified)",
+ "Programming Language :: Python :: 3",
+ "Programming Language :: Python :: 3.8",
+ "Programming Language :: Python :: 3.9",
+ "Programming Language :: Python :: 3.10",
+ "Programming Language :: Python :: 3.11",
+ "Programming Language :: Python :: 3.12",
+ "Programming Language :: Python :: 3.13",
+ "Topic :: Utilities",
+]
+dependencies = [
+ "paddlex[ocr-core]>=3.7.0,<3.8.0",
+ "PyYAML>=6",
+ "requests",
+ "aiohttp>=3.8.0",
+ "typing-extensions>=4.12",
+]
+
+[project.urls]
+homepage = "https://github.com/PaddlePaddle/PaddleOCR"
+documentation = "https://github.com/PaddlePaddle/PaddleOCR/blob/main/README.md"
+repository = "https://github.com/PaddlePaddle/PaddleOCR.git"
+issues = "https://github.com/PaddlePaddle/PaddleOCR/issues"
+
+[project.scripts]
+paddleocr = "paddleocr.__main__:console_entry"
+
+[project.optional-dependencies]
+doc-parser = ["paddlex[ocr,genai-client]>=3.7.0,<3.8.0"]
+ie = ["paddlex[ie]>=3.7.0,<3.8.0"]
+trans = ["paddlex[trans]>=3.7.0,<3.8.0"]
+doc2md = ["python-docx>=0.8.11", "python-pptx>=0.6.21", "openpyxl>=3.0.0", "pylatexenc>=2.10,<3"]
+all = ["paddlex[ocr,genai-client,ie,trans]>=3.7.0,<3.8.0", "python-docx>=0.8.11", "python-pptx>=0.6.21", "openpyxl>=3.0.0"]
+
+[tool.setuptools.packages.find]
+where = ["."]
+include = ["paddleocr", "paddleocr.*"]
+namespaces = false
+
+[tool.setuptools_scm]
+version_scheme = 'release-branch-semver'
+git_describe_command = ["git", "describe", "--dirty", "--tags", "--long", "--match", "v[0-9]*"]
+
+[tool.pytest.ini_options]
+markers = [
+ "resource_intensive: mark a test as resource intensive",
+ "py38_incompatible: test requires extras or deps that need Python 3.9+"
+]
+addopts = "-m 'not resource_intensive'"
diff --git a/ocr-studio/PaddleOCR/readme/README_ar.md b/ocr-studio/PaddleOCR/readme/README_ar.md
new file mode 100644
index 0000000000000000000000000000000000000000..e5314f97d58a1590edf7516ef6f53498a4757db6
--- /dev/null
+++ b/ocr-studio/PaddleOCR/readme/README_ar.md
@@ -0,0 +1,305 @@
+
+
+
+
+  +
+
+
+
+
مجموعة أدوات التعرف الضوئي على الحروف (OCR) الرائدة عالمياً ومحرك الذكاء الاصطناعي للمستندات
+
+[English](../README.md) | [简体中文](./README_cn.md) | [繁體中文](./README_tcn.md) | [日本語](./README_ja.md) | [한국어](./README_ko.md) | [Français](./README_fr.md) | [Русский](./README_ru.md) | [Español](./README_es.md) | العربية
+
+
+
+[](https://pepy.tech/projects/paddleocr)
+[](https://github.com/PaddlePaddle/PaddleOCR/network/dependents)
+
+
+
+
+[](https://www.paddleocr.com)
+[](https://deepwiki.com/PaddlePaddle/PaddleOCR)
+[](../LICENSE)
+
+
+
+  +
+
+2026.05.28: إصدار PaddleOCR 3.6.0
+
+- أبرز مزايا PaddleOCR-VL-1.6:
+
+ - **دقة SOTA جديدة**: 96.3% على OmniDocBench v1.6، SOTA جديد على OmniDocBench v1.5 وReal5-OmniDocBench.
+ - **ترقية شاملة**: تحسينات كبيرة في الجداول والمستندات القديمة والأحرف النادرة.
+ - **ترحيل سلس**: بنية متوافقة تماماً مع PaddleOCR-VL-1.5.
+ - **جرّبه الآن**: [HuggingFace](https://huggingface.co/PaddlePaddle/PaddleOCR-VL-1.6) أو [الموقع الرسمي](https://www.paddleocr.com).
+
+
+
+2026.04.21: إصدار PaddleOCR 3.5.0
+
+* **مرونة أكبر في تبديل واجهات الاستدلال**: يدعم التبديل السلس بين الرسم البياني الثابت في Paddle، والرسم البياني الديناميكي في Paddle، وTransformers. أصبح PaddleOCR الآن متكاملاً بعمق مع منظومة Hugging Face، كما تدعم 20 من النماذج الرئيسية استخدام Transformers كواجهة للاستدلال.
+* **تحويل مستندات Office إلى Markdown**: يدعم تحويل صيغ المستندات الشائعة مثل Word وExcel وPowerPoint إلى Markdown.
+* **تصدير نتائج التحليل إلى DOCX**: أصبحت سلاسل `PaddleOCR-VL` و`PP-StructureV3` و`PP-DocTranslation` تدعم الآن تصدير نتائج التحليل إلى DOCX لسهولة العرض والتحرير في Microsoft Word.
+* **حزمة SDK الرسمية للاستدلال في المتصفح**: تم إصدار `PaddleOCR.js`، وهي حزمة SDK الرسمية للاستدلال في المتصفح، وتدعم تشغيل `PP-OCRv5` مباشرة داخل المتصفح.
+
+
+
+
+2026.01.29: إصدار PaddleOCR 3.4.0
+* PaddleOCR-VL-1.5 (نموذج VLM رائد بحجم 0.9B): نموذجنا الرائد الأحدث لتحليل المستندات متاح الآن!
+ * **دقة 94.5% على OmniDocBench**: يتفوق على النماذج الكبيرة العامة الرائدة ومحللات المستندات المتخصصة.
+ * **متانة في العالم الواقعي**: أول من يقدم خوارزمية **PP-DocLayoutV3** لتحديد موقع الأشكال غير المنتظمة، مع إتقان 5 سيناريوهات صعبة: *الميل، التشوه، المسح الضوئي، الإضاءة، وتصوير الشاشة*.
+ * **توسيع القدرات**: يدعم الآن **التعرف على الأختام**، و**الكشف عن النصوص**، ويتوسع ليشمل **111 لغة** (بما في ذلك الخط التبتي الصيني والبنغالية).
+ * **إتقان المستندات الطويلة**: يدعم الدمج التلقائي للجداول عبر الصفحات وتحديد العناوين الهرمية.
+ * **جرّبه الآن**: متاح على [HuggingFace](https://huggingface.co/PaddlePaddle/PaddleOCR-VL-1.5) أو [موقعنا الرسمي](https://www.paddleocr.com).
+
+
+
+
+2025.10.16: إصدار PaddleOCR 3.3.0
+
+- إصدار PaddleOCR-VL:
+ - **تقديم النموذج**:
+ - **PaddleOCR-VL** هو نموذج رائد وموفر للموارد مصمم خصيصاً لتحليل المستندات. مكونه الأساسي هو PaddleOCR-VL-0.9B، وهو نموذج رؤية-لغة (VLM) صغير الحجم لكنه قوي يدمج مشفر بصري ديناميكي الدقة بأسلوب NaViT مع النموذج اللغوي ERNIE-4.5-0.3B لتمكين التعرف الدقيق على العناصر. **يدعم هذا النموذج المبتكر 109 لغات بكفاءة ويتفوق في التعرف على العناصر المعقدة (مثل النصوص والجداول والصيغ الرياضية والرسوم البيانية)، مع الحفاظ على الحد الأدنى من استهلاك الموارد**. من خلال التقييمات الشاملة على المعايير المرجعية العامة المستخدمة على نطاق واسع والمعايير الداخلية، يحقق PaddleOCR-VL أداءً رائداً في كل من تحليل المستندات على مستوى الصفحة والتعرف على العناصر. يتفوق بشكل كبير على الحلول الحالية، ويُظهر تنافسية قوية أمام نماذج VLM الرائدة، ويقدم سرعات استدلال عالية. هذه المزايا تجعله مناسباً جداً للنشر العملي في السيناريوهات الواقعية. تم إصدار النموذج على [HuggingFace](https://huggingface.co/PaddlePaddle/PaddleOCR-VL). نرحب بالجميع لتنزيله واستخدامه! يمكن العثور على مزيد من المعلومات في [PaddleOCR-VL](https://www.paddleocr.ai/latest/version3.x/algorithm/PaddleOCR-VL/PaddleOCR-VL.html).
+
+ - **الميزات الأساسية**:
+ - **بنية VLM صغيرة لكنها قوية**: نقدم نموذج رؤية-لغة مبتكراً مصمماً خصيصاً للاستدلال الموفر للموارد، يحقق أداءً متميزاً في التعرف على العناصر. من خلال دمج مشفر بصري ديناميكي عالي الدقة بأسلوب NaViT مع النموذج اللغوي خفيف الحجم ERNIE-4.5-0.3B، نعزز بشكل كبير قدرات التعرف وكفاءة فك التشفير. يحافظ هذا الدمج على دقة عالية مع تقليل المتطلبات الحسابية، مما يجعله مناسباً تماماً لتطبيقات معالجة المستندات الفعالة والعملية.
+ - **أداء رائد في تحليل المستندات**: يحقق PaddleOCR-VL أداءً رائداً في كل من تحليل المستندات على مستوى الصفحة والتعرف على العناصر. يتفوق بشكل كبير على الحلول القائمة على خطوط الأنابيب ويُظهر تنافسية قوية أمام نماذج الرؤية-اللغة (VLMs) الرائدة في تحليل المستندات. علاوة على ذلك، يتفوق في التعرف على عناصر المستندات المعقدة، مثل النصوص والجداول والصيغ الرياضية والرسوم البيانية، مما يجعله مناسباً لمجموعة واسعة من أنواع المحتوى الصعبة، بما في ذلك النصوص المكتوبة بخط اليد والمستندات التاريخية. وهذا يجعله متعدد الاستخدامات ومناسباً لمجموعة واسعة من أنواع المستندات والسيناريوهات.
+ - **دعم متعدد اللغات**: يدعم PaddleOCR-VL 109 لغات، تغطي اللغات العالمية الرئيسية، بما في ذلك على سبيل المثال لا الحصر الصينية والإنجليزية واليابانية واللاتينية والكورية، بالإضافة إلى لغات ذات خطوط وبنى مختلفة مثل الروسية (الخط السيريلي) والعربية والهندية (خط ديفاناغاري) والتايلاندية. تعزز هذه التغطية اللغوية الواسعة بشكل كبير من قابلية تطبيق نظامنا في سيناريوهات معالجة المستندات متعددة اللغات والعالمية.
+
+- إصدار نموذج التعرف متعدد اللغات PP-OCRv5:
+ - تحسين دقة وتغطية التعرف على الخط اللاتيني؛ إضافة دعم للأنظمة الكتابية السيريلية والعربية والديفاناغارية والتيلوغية والتاميلية وغيرها، مع تغطية التعرف على 109 لغات. يحتوي النموذج على 2 مليون معامل فقط، وقد زادت دقة بعض النماذج بأكثر من 40% مقارنة بالجيل السابق.
+
+
+
+
+
+2025.08.21: إصدار PaddleOCR 3.2.0
+
+- **إضافات نموذجية مهمة:**
+ - تقديم التدريب والاستدلال والنشر لنماذج التعرف PP-OCRv5 باللغات الإنجليزية والتايلاندية واليونانية. **يقدم نموذج PP-OCRv5 الإنجليزي تحسيناً بنسبة 11% في السيناريوهات الإنجليزية مقارنة بنموذج PP-OCRv5 الرئيسي، مع تحقيق نماذج التعرف التايلاندي واليوناني دقة 82.68% و89.28% على التوالي.**
+
+- **ترقيات قدرات النشر:**
+ - **دعم كامل لإصداري إطار عمل PaddlePaddle 3.1.0 و3.1.1.**
+ - **ترقية شاملة لحل النشر المحلي بلغة C++ لـ PP-OCRv5، يدعم الآن كلاً من Linux وWindows، مع تكافؤ الميزات ودقة مطابقة لتنفيذ Python.**
+ - **يدعم الاستدلال عالي الأداء الآن CUDA 12، ويمكن إجراء الاستدلال باستخدام واجهة Paddle Inference أو ONNX Runtime.**
+ - **حل النشر الخدمي عالي الاستقرار أصبح الآن مفتوح المصدر بالكامل، مما يتيح للمستخدمين تخصيص صور Docker وحزم SDK حسب الحاجة.**
+ - يدعم حل النشر الخدمي عالي الاستقرار أيضاً الاستدعاء عبر طلبات HTTP المُنشأة يدوياً، مما يتيح تطوير الشيفرة البرمجية من جانب العميل بأي لغة برمجة.
+
+- **دعم المعايير المرجعية:**
+ - **تدعم جميع خطوط الإنتاج الآن قياس الأداء الدقيق، مما يتيح قياس زمن الاستدلال الشامل بالإضافة إلى بيانات زمن الاستجابة لكل طبقة ووحدة للمساعدة في تحليل الأداء. [إليك](docs/version3.x/pipeline_usage/instructions/benchmark.en.md) كيفية إعداد واستخدام ميزة قياس الأداء.**
+ - **تم تحديث الوثائق لتشمل المقاييس الرئيسية للتكوينات الشائعة الاستخدام على العتاد الرئيسي، مثل زمن الاستجابة واستخدام الذاكرة، لتوفير مراجع النشر للمستخدمين.**
+
+- **إصلاح الأخطاء:**
+ - حل مشكلة فشل حفظ السجلات أثناء تدريب النموذج.
+ - ترقية مكون تعزيز البيانات لنماذج الصيغ الرياضية للتوافق مع الإصدارات الأحدث من مكتبة albumentations، وإصلاح تحذيرات الجمود عند استخدام حزمة tokenizers في سيناريوهات متعددة العمليات.
+ - إصلاح التناقضات في سلوكيات المفاتيح (مثل `use_chart_parsing`) في ملفات تكوين PP-StructureV3 مقارنة بخطوط الأنابيب الأخرى.
+
+- **تحسينات أخرى:**
+ - **فصل التبعيات الأساسية والاختيارية. التبعيات الأساسية الدنيا فقط مطلوبة للتعرف الأساسي على النصوص؛ يمكن تثبيت التبعيات الإضافية لتحليل المستندات واستخراج المعلومات حسب الحاجة.**
+ - **تمكين دعم بطاقات الرسومات NVIDIA RTX من سلسلة 50 على Windows؛ يمكن للمستخدمين الرجوع إلى [دليل التثبيت](docs/version3.x/installation.en.md) لإصدارات إطار PaddlePaddle المقابلة.**
+ - **تدعم نماذج سلسلة PP-OCR الآن إرجاع إحداثيات الأحرف المفردة.**
+ - إضافة مصادر تنزيل النماذج من AIStudio وModelScope وغيرها، مما يتيح للمستخدمين تحديد مصدر تنزيل النماذج.
+ - إضافة دعم تحويل الرسوم البيانية إلى جداول عبر وحدة PP-Chart2Table.
+ - تحسين أوصاف الوثائق لتعزيز قابلية الاستخدام.
+
+
+
+[سجل التحديثات](https://paddlepaddle.github.io/PaddleOCR/latest/en/update/update.html)
+
+
+## 🚀 بداية سريعة
+
+### الخطوة 1: جرّب عبر الإنترنت
+يوفر الموقع الرسمي لـ PaddleOCR **مركز تجربة** تفاعلي و**واجهات برمجة التطبيقات (APIs)** — لا حاجة لأي إعداد، فقط انقر لتجربة الخدمة.
+
+👉 [زيارة الموقع الرسمي](https://www.paddleocr.com)
+
+### الخطوة 2: النشر المحلي
+للاستخدام المحلي، يُرجى الرجوع إلى الوثائق التالية بناءً على احتياجاتك:
+
+- **سلسلة PP-OCR**: انظر [وثائق PP-OCR](https://www.paddleocr.ai/latest/en/version3.x/pipeline_usage/OCR.html)
+- **سلسلة PaddleOCR-VL**: انظر [وثائق PaddleOCR-VL](https://www.paddleocr.ai/latest/en/version3.x/pipeline_usage/PaddleOCR-VL.html)
+- **PP-StructureV3**: انظر [وثائق PP-StructureV3](https://www.paddleocr.ai/latest/en/version3.x/pipeline_usage/PP-StructureV3.html)
+- **المزيد من القدرات**: انظر [وثائق المزيد من القدرات](https://www.paddleocr.ai/latest/en/version3.x/pipeline_usage/pipeline_overview.html)
+
+
+## 🧩 المزيد من الميزات
+
+- تحويل النماذج إلى صيغة ONNX: [الحصول على نماذج ONNX](https://paddlepaddle.github.io/PaddleOCR/latest/en/version3.x/inference_deployment/others/obtaining_onnx_models.html).
+- تسريع الاستدلال باستخدام محركات مثل OpenVINO وONNX Runtime وTensorRT، أو إجراء الاستدلال باستخدام نماذج بصيغة ONNX: [الاستدلال عالي الأداء](https://paddlepaddle.github.io/PaddleOCR/latest/en/version3.x/inference_deployment/local_inference/high_performance_inference.html).
+- تسريع الاستدلال باستخدام وحدات GPU متعددة وعمليات متعددة: [الاستدلال المتوازي لخطوط الأنابيب](https://paddlepaddle.github.io/PaddleOCR/latest/en/version3.x/pipeline_usage/instructions/parallel_inference.html).
+- دمج PaddleOCR في تطبيقات مكتوبة بلغات C++ وC# وJava وغيرها: [الخدمة](https://paddlepaddle.github.io/PaddleOCR/latest/en/version3.x/inference_deployment/serving/serving.html).
+
+## 🔄 نظرة سريعة على نتائج التنفيذ
+
+### PP-OCRv5
+
+
+
+  +
+
+
+  +
+
+
+  +
+
+
+  +
+
+
+| حساب PaddlePaddle الرسمي على WeChat | انضم إلى مجموعة النقاش التقني |
+| :---: | :---: |
+|

|

|
+
+
+| اسم المشروع | الوصف |
+| ------------ | ----------- |
+| [Dify](https://github.com/langgenius/dify)

|منصة جاهزة للإنتاج لتطوير سير العمل الوكيلي.|
+| [RAGFlow](https://github.com/infiniflow/ragflow)

|محرك RAG قائم على الفهم العميق للمستندات.|
+| [pathway](https://github.com/pathwaycom/pathway)

|إطار عمل Python ETL لمعالجة التدفقات والتحليلات الآنية وخطوط أنابيب النماذج اللغوية الكبيرة وRAG.|
+| [MinerU](https://github.com/opendatalab/MinerU)

|أداة تحويل المستندات متعددة الأنواع إلى Markdown.|
+| [Umi-OCR](https://github.com/hiroi-sora/Umi-OCR)

|برنامج OCR مجاني، مفتوح المصدر، للمعالجة الدفعية دون اتصال بالإنترنت.|
+| [cherry-studio](https://github.com/CherryHQ/cherry-studio)

|تطبيق سطح مكتب يدعم مزودي نماذج لغوية كبيرة متعددين.|
+| [haystack](https://github.com/deepset-ai/haystack)

|إطار عمل لتنظيم الذكاء الاصطناعي لبناء تطبيقات نماذج لغوية كبيرة قابلة للتخصيص وجاهزة للإنتاج.|
+| [OmniParser](https://github.com/microsoft/OmniParser)

|OmniParser: أداة تحليل الشاشة لوكيل واجهة المستخدم الرسومية القائم على الرؤية البحتة.|
+| [QAnything](https://github.com/netease-youdao/QAnything)

|الأسئلة والأجوبة المبنية على أي شيء.|
+| [تعرّف على المزيد من المشاريع](./awesome_projects.md) | [المزيد من المشاريع المبنية على PaddleOCR](./awesome_projects.md)|
+
+
+  +
+
+
+
+
+
+
+
+
全球领先的 OCR 工具包与文档 AI 引擎
+
+[English](../README.md) | 简体中文| [繁體中文](./README_tcn.md) | [日本語](./README_ja.md) | [한국어](./README_ko.md) | [Français](./README_fr.md) | [Русский](./README_ru.md) | [Español](./README_es.md) | [العربية](./README_ar.md)
+
+
+
+[](https://pepy.tech/projects/paddleocr)
+[](https://github.com/PaddlePaddle/PaddleOCR/network/dependents)
+
+
+
+
+[](https://www.paddleocr.com)
+[](https://deepwiki.com/PaddlePaddle/PaddleOCR)
+[](../LICENSE)
+
+
+
+ 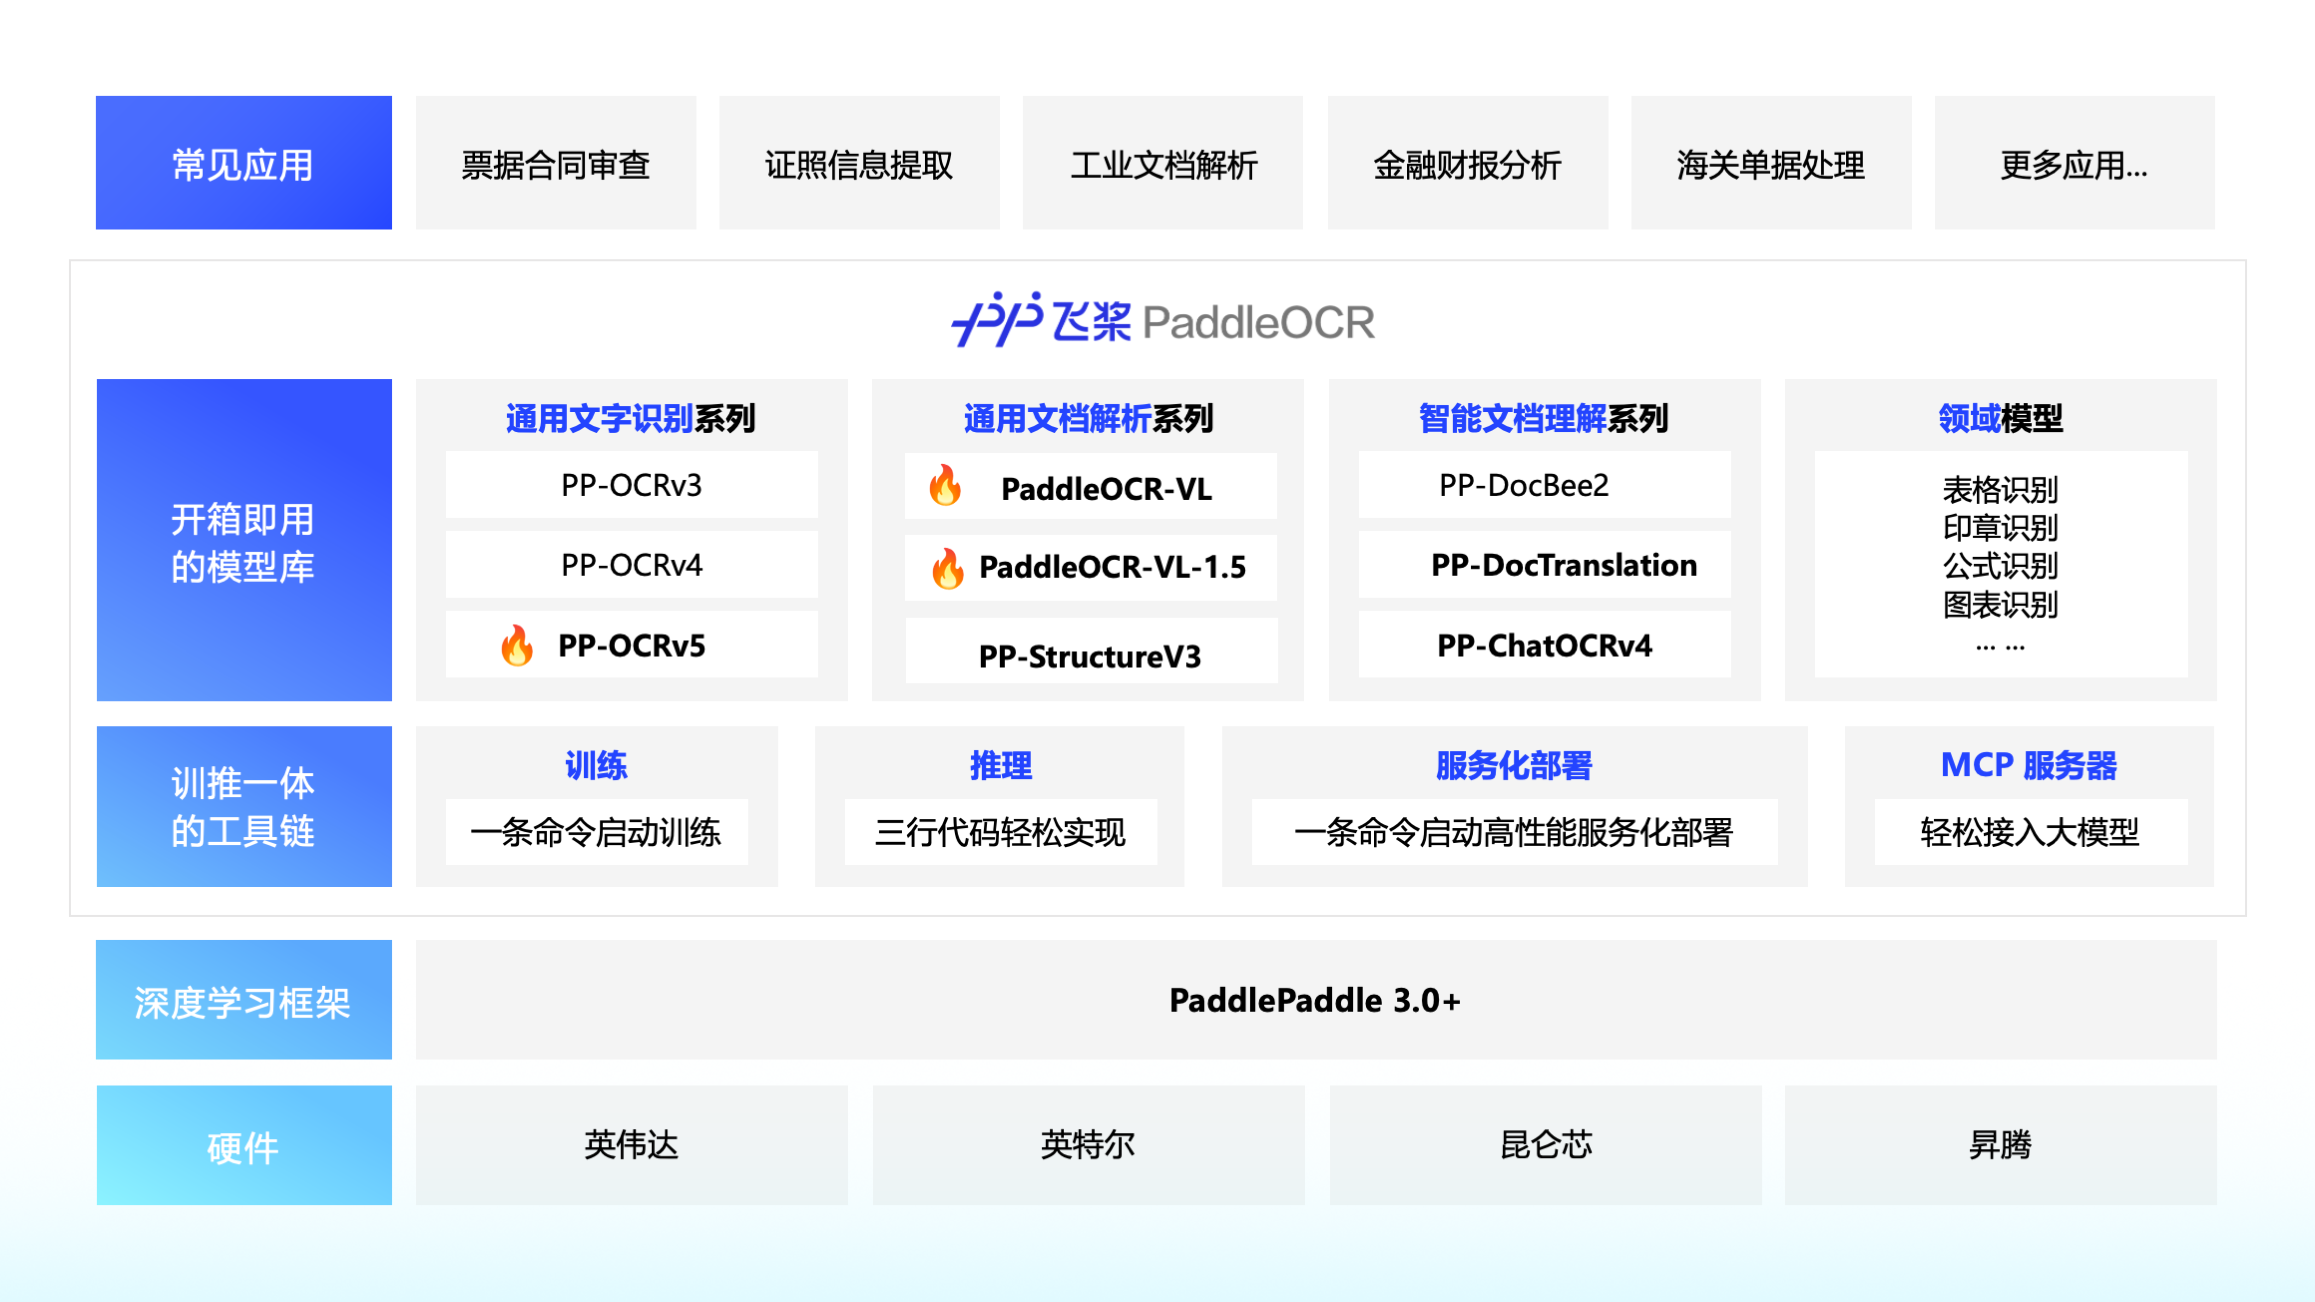 +
+
+2026.05.28: PaddleOCR 3.6.0 发布
+
+- PaddleOCR-VL-1.6核心亮点如下:
+
+ - **全新SOTA精度**:OmniDocBench v1.6 突破96.3%,在OmniDocBench v1.5、Real5-OmniDocBench上同样刷新SOTA,文本、公式、表格识别全面领先开源与闭源方案。
+ - **能力全面升级**:表格、古籍、生僻字识别大幅提升,印章、spotting、图表识别等多场景均有显著增强。
+ - **无缝迁移**:模型结构与PaddleOCR-VL-1.5完全一致,零成本适配,即换即用。
+ - **立即试用**:可在 [HuggingFace](https://huggingface.co/PaddlePaddle/PaddleOCR-VL-1.6) 或 [PaddleOCR 官方网站](https://www.paddleocr.com) 使用。
+
+
+
+
+2026.04.21: PaddleOCR 3.5.0 发布
+
+* **推理后端灵活切换**:支持在飞桨静态图、飞桨动态图和 Transformers 之间无缝切换。深度适配 Hugging Face 生态,20 个主要模型支持以 Transformers 作为推理后端。
+* **常见文档格式转 Markdown**:支持将 Word、Excel、Powerpoint 等常见文档格式转换为 Markdown。
+* **解析结果导出 DOCX**:`PaddleOCR-VL` 系列、`PP-StructureV3` 和 `PP-DocTranslation` 现已支持将解析结果导出为 DOCX,便于在 Microsoft Word 中查看和编辑。
+* **官方浏览器推理 SDK**:发布官方浏览器推理 SDK `PaddleOCR.js`,支持在浏览器中运行 `PP-OCRv5`。
+
+
+
+
+2026.01.29: PaddleOCR 3.4.0 发布
+* PaddleOCR-VL-1.5 (SOTA 0.9B VLM):
+ * **OmniDocBench 94.5%准确率**:超越顶级通用大模型和专业文档解析模型。
+ * **现实5大场景文档解析的SOTA性能**:首次引入**PP-DocLayoutV3**算法进行异形框定位,可以解决5种真实场景: 倾斜、弯曲、扫描、光线变化和屏幕拍照。
+ * **能力拓展**:增加**印章识别**、**文本行检测/识别**,并扩展至**111种语言**(包括中国的藏文和孟加拉语)。
+ * **长文档跨页解析**:支持自动跨页表格合并和分层标题识别。
+ * **立即试用**:可在[HuggingFace](https://huggingface.co/PaddlePaddle/PaddleOCR-VL-1.5)或[PaddleOCR 官方网站](https://www.paddleocr.com)使用。
+
+
+
+
+2025.10.16: PaddleOCR 3.3.0 发布
+
+- **发布PaddleOCR-VL**:
+ - **模型介绍**:
+ - **PaddleOCR-VL** 是一款先进、高效的文档解析模型,专为文档中的元素识别设计。其核心组件为 PaddleOCR-VL-0.9B,这是一种紧凑而强大的视觉语言模型(VLM),它由 NaViT 风格的动态分辨率视觉编码器与 ERNIE-4.5-0.3B 语言模型组成,能够实现精准的元素识别。**该模型支持 109 种语言,并在识别复杂元素(如文本、表格、公式和图表)方面表现出色,同时保持极低的资源消耗。通过在广泛使用的公开基准与内部基准上的全面评测,PaddleOCR-VL 在页级级文档解析与元素级识别均达到 SOTA 表现**。它显著优于现有的基于Pipeline方案和文档解析多模态方案以及先进的通用多模态大模型,并具备更快的推理速度。这些优势使其非常适合在真实场景中落地部署。模型已发布至[HuggingFace](https://huggingface.co/PaddlePaddle/PaddleOCR-VL),欢迎大家下载使用!更多介绍内容请点击[PaddleOCR-VL](https://www.paddleocr.ai/latest/version3.x/algorithm/PaddleOCR-VL/PaddleOCR-VL.html)。
+
+ - **特性**:
+ - **紧凑而强大的视觉语言模型架构**:我们提出了一种新的视觉语言模型,专为资源高效的推理而设计,在元素识别方面表现出色。通过将NaViT风格的动态高分辨率视觉编码器与轻量级的ERNIE-4.5-0.3B语言模型结合,我们显著增强了模型的识别能力和解码效率。这种集成在保持高准确率的同时降低了计算需求,使其非常适合高效且实用的文档处理应用。
+ - **文档解析的SOTA性能**:PaddleOCR-VL在页面级文档解析和元素级识别中达到了最先进的性能。它显著优于现有的基于流水线的解决方案,并在文档解析中展现出与领先的视觉语言模型(VLMs)竞争的强劲实力。此外,它在识别复杂的文档元素(如文本、表格、公式和图表)方面表现出色,使其适用于包括手写文本和历史文献在内的各种具有挑战性的内容类型。这使得它具有高度的多功能性,适用于广泛的文档类型和场景。
+ - **多语言支持**:PaddleOCR-VL支持109种语言,覆盖了主要的全球语言,包括但不限于中文、英文、日文、拉丁文和韩文,以及使用不同文字和结构的语言,如俄语(西里尔字母)、阿拉伯语、印地语(天城文)和泰语。这种广泛的语言覆盖大大增强了我们系统在多语言和全球化文档处理场景中的适用性。
+
+- **发布PP-OCRv5小语种识别模型**:
+ - 优化拉丁文识别的准度和广度,新增西里尔文、阿拉伯文、天城文、泰卢固语、泰米尔语等语系,覆盖109种语言文字的识别。模型参数量仅为2M,部分模型精度较上一代提升40%以上。
+
+
+
+
+
+2025.08.21: PaddleOCR 3.2.0 发布
+
+- **重要模型新增:**
+ - 新增 PP-OCRv5 英文、泰文、希腊文识别模型的训练、推理、部署。**其中 PP-OCRv5 英文模型较 PP-OCRv5 主模型在英文场景提升 11%,泰文识别模型精度 82.68%,希腊文识别模型精度 89.28%。**
+
+- **部署能力升级:**
+ - **全面支持飞桨框架 3.1.0 和 3.1.1 版本。**
+ - **全面升级 PP-OCRv5 C++ 本地部署方案,支持 Linux、Windows,功能及精度效果与 Python 方案保持一致。**
+ - **高性能推理支持 CUDA 12,可使用 Paddle Inference、ONNX Runtime 后端推理。**
+ - **高稳定性服务化部署方案全面开源,支持用户根据需求对 Docker 镜像和 SDK 进行定制化修改。**
+ - 高稳定性服务化部署方案支持通过手动构造HTTP请求的方式调用,该方式允许客户端代码使用任意编程语言编写。
+
+- **Benchmark支持**:
+ - **全部产线支持产线细粒度 benchmark,能够测量产线端到端推理时间以及逐层、逐模块的耗时数据,可用于辅助产线性能分析。可以参考[文档](../docs/version3.x/pipeline_usage/instructions/benchmark.md)来进行性能测试。**
+ - **文档中补充各产线常用配置在主流硬件上的关键指标,包括推理耗时和内存占用等,为用户部署提供参考。**
+
+- **Bug修复:**
+ - 修复模型训练时训练日志保存失败的问题。
+ - 对公式模型的数据增强部分进行了版本兼容性升级,以适应新版本的 albumentations 依赖,并修复了在多进程使用 tokenizers 依赖包时出现的死锁警告。
+ - 修复 PP-StructureV3 配置文件中的 `use_chart_parsing` 等开关行为与其他产线不统一的问题。
+
+- **其他升级:**
+ - **分离必要依赖与可选依赖。使用基础文字识别功能时,仅需安装少量核心依赖;若需文档解析、信息抽取等功能,用户可按需选择安装额外依赖。**
+ - **支持 Windows 用户使用英伟达 50 系显卡,可根据 [安装文档](../docs/version3.x/installation.md) 安装对应版本的 paddle 框架。**
+ - **PP-OCR 系列模型支持返回单文字坐标。**
+ - 模型新增 AIStudio、ModelScope 等下载源。可指定相关下载源下载对应的模型。
+ - 支持图表转表 PP-Chart2Table 单功能模块推理能力。
+ - 优化部分使用文档中的描述,提升易用性。
+
+
+
+[历史日志](https://paddlepaddle.github.io/PaddleOCR/latest/en/update/update.html)
+
+
+## 🚀 快速开始
+
+### 步骤 1: 在线体验
+PaddleOCR官方网站提供交互式**体验中心**和**APIs**——无需设置,一键体验。
+
+👉 [访问官方网站](https://www.paddleocr.com)
+
+### 步骤 2: 本地部署
+
+对于本地使用,请根据您的需求参考以下文档:
+
+- **PP-OCR系列**:查看[PP-OCR文档](https://www.paddleocr.ai/latest/version3.x/pipeline_usage/OCR.html)
+- **PaddleOCR-VL系列**:查看[PaddleOCR-VL文档](https://www.paddleocr.ai/latest/version3.x/pipeline_usage/PaddleOCR-VL.html)
+- **PP-StructureV3**:查看[PP-StructureV3文档](https://www.paddleocr.ai/latest/version3.x/pipeline_usage/PP-StructureV3.html)
+- **更多能力**:查看[更多能力文档](https://www.paddleocr.ai/latest/version3.x/pipeline_usage/pipeline_overview.html)
+
+
+## 🧩 更多功能
+
+- 将模型转换为ONNX格式: [获取ONNX模型](https://paddlepaddle.github.io/PaddleOCR/latest/version3.x/inference_deployment/others/obtaining_onnx_models.html)。
+- 使用OpenVINO、ONNX Runtime、TensorRT等引擎加速推理,或使用ONNX格式模型进行推理: [高性能推理](https://paddlepaddle.github.io/PaddleOCR/latest/version3.x/inference_deployment/local_inference/high_performance_inference.html)。
+- 使用多GPU和多进程加速推理: [流水线并行推理](https://paddlepaddle.github.io/PaddleOCR/latest/version3.x/pipeline_usage/instructions/parallel_inference.html)。
+- 将PaddleOCR集成到C++、C#、Java等语言编写的应用程序中: [服务化部署](https://paddlepaddle.github.io/PaddleOCR/latest/version3.x/inference_deployment/serving/serving.html)。
+
+## 🔄 执行结果快速预览
+
+### PP-OCRv5
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+| PaddlePaddle 微信公众号 | 加入技术讨论群 |
+| :---: | :---: |
+|
|
|
+
+
+PaddleOCR 的发展离不开社区贡献!💗衷心感谢所有开发者、合作伙伴与贡献者!
+| 项目名称 | 简介 |
+| ------------ | ----------- |
+| [RAGFlow](https://github.com/infiniflow/ragflow)
|基于RAG的AI工作流引擎|
+| [pathway](https://github.com/pathwaycom/pathway)
|用于流处理、实时分析、LLM流水线和RAG的Python ETL框架|
+| [MinerU](https://github.com/opendatalab/MinerU)
|多类型文档转换Markdown工具|
+| [Umi-OCR](https://github.com/hiroi-sora/Umi-OCR)
|开源批量离线OCR软件|
+| [cherry-studio](https://github.com/CherryHQ/cherry-studio)
|一个支持多个LLM提供商的桌面客户端|
+| [OmniParser](https://github.com/microsoft/OmniParser)
|基于纯视觉的GUI智能体屏幕解析工具|
+| [QAnything](https://github.com/netease-youdao/QAnything)
|基于任意内容的问答系统|
+| [PDF-Extract-Kit](https://github.com/opendatalab/PDF-Extract-Kit)

|高效复杂PDF文档提取工具包|
+| [Dango-Translator](https://github.com/PantsuDango/Dango-Translator)

|屏幕实时翻译工具|
+| [更多项目](../awesome_projects.md) | [更多基于PaddleOCR的项目](../awesome_projects.md) |
+
+
+
+
+
+
+
+
+
+
+
+
Kit de OCR líder mundial y motor de IA para documentos
+
+[English](../README.md) | [简体中文](./README_cn.md) | [繁體中文](./README_tcn.md) | [日本語](./README_ja.md) | [한국어](./README_ko.md) | [Français](./README_fr.md) | [Русский](./README_ru.md) | Español | [العربية](./README_ar.md)
+
+
+
+[](https://pepy.tech/projects/paddleocr)
+[](https://github.com/PaddlePaddle/PaddleOCR/network/dependents)
+
+
+
+
+[](https://www.paddleocr.com)
+[](https://deepwiki.com/PaddlePaddle/PaddleOCR)
+[](../LICENSE)
+
+
+
+
+
+
+2026.05.28: Lanzamiento de PaddleOCR 3.6.0
+
+- Aspectos destacados de PaddleOCR-VL-1.6:
+
+ - **Nueva precisión SOTA**: 96.3% en OmniDocBench v1.6, nuevo SOTA en OmniDocBench v1.5 y Real5-OmniDocBench.
+ - **Mejora integral**: mejoras significativas en tablas, documentos antiguos y caracteres raros.
+ - **Migración sin fisuras**: arquitectura totalmente compatible con PaddleOCR-VL-1.5.
+ - **Pruébalo**: [HuggingFace](https://huggingface.co/PaddlePaddle/PaddleOCR-VL-1.6) o [sitio oficial](https://www.paddleocr.com).
+
+
+
+2026.04.21: Lanzamiento de PaddleOCR 3.5.0
+
+* **Backends de inferencia más flexibles**: cambia sin problemas entre grafo estático de Paddle, grafo dinámico de Paddle y Transformers. PaddleOCR está ahora profundamente integrado con el ecosistema de Hugging Face, y 20 modelos principales admiten Transformers como backend de inferencia.
+* **Documentos de Office a Markdown**: convierte formatos de documentos comunes como Word, Excel y PowerPoint a Markdown.
+* **Exportación de resultados a DOCX**: las series `PaddleOCR-VL`, `PP-StructureV3` y `PP-DocTranslation` ahora admiten exportar los resultados de análisis a DOCX para verlos y editarlos cómodamente en Microsoft Word.
+* **SDK oficial de inferencia en navegador**: se lanzó `PaddleOCR.js`, el SDK oficial de inferencia en navegador, que permite ejecutar `PP-OCRv5` directamente en el navegador.
+
+
+
+
+2026.01.29: Lanzamiento de PaddleOCR 3.4.0
+* PaddleOCR-VL-1.5 (SOTA 0,9B VLM): ¡Nuestro último modelo insignia para el análisis de documentos ya está disponible!
+ * **94,5% de precisión en OmniDocBench**: Superando a los mejores modelos generales de gran escala y a los analizadores de documentos especializados.
+ * **Robustez en el mundo real**: El primero en introducir el algoritmo **PP-DocLayoutV3** para el posicionamiento de formas irregulares, dominando 5 escenarios difíciles: *inclinación, deformación, escaneo, iluminación y fotografía de pantalla*.
+ * **Expansión de capacidades**: Ahora admite **reconocimiento de sellos**, **detección de texto** y se expande a **111 idiomas** (incluyendo el tibetano de China y el bengalí).
+ * **Dominio de documentos largos**: Admite la fusión automática de tablas entre páginas e identificación jerárquica de encabezados.
+ * **Pruébalo ahora**: Disponible en [HuggingFace](https://huggingface.co/PaddlePaddle/PaddleOCR-VL-1.5) o en nuestro [Sitio web oficial](https://www.paddleocr.com).
+
+
+
+
+2025.10.16: Lanzamiento de PaddleOCR 3.3.0
+
+- Lanzamiento de PaddleOCR-VL:
+ - **Introducción al modelo**:
+ - **PaddleOCR-VL** es un modelo SOTA eficiente en recursos diseñado específicamente para el análisis de documentos. Su componente principal es PaddleOCR-VL-0.9B, un modelo de visión y lenguaje (VLM) compacto pero potente que integra un codificador visual de resolución dinámica al estilo NaViT con el modelo de lenguaje ERNIE-4.5-0.3B para permitir un reconocimiento preciso de elementos. **Este innovador modelo admite eficientemente 109 idiomas y sobresale en el reconocimiento de elementos complejos (p. ej., texto, tablas, fórmulas y gráficos), mientras mantiene un consumo mínimo de recursos**. A través de evaluaciones exhaustivas en benchmarks públicos ampliamente utilizados y benchmarks internos, PaddleOCR-VL logra un rendimiento SOTA tanto en el análisis de documentos a nivel de página como en el reconocimiento a nivel de elemento. Supera significativamente a las soluciones existentes, exhibe una fuerte competitividad frente a los VLM de primer nivel y ofrece velocidades de inferencia rápidas. Estas fortalezas lo hacen altamente adecuado para el despliegue práctico en escenarios del mundo real. El modelo ha sido publicado en [HuggingFace](https://huggingface.co/PaddlePaddle/PaddleOCR-VL). ¡Todos son bienvenidos a descargarlo y usarlo! Más información de introducción se puede encontrar en [PaddleOCR-VL](https://www.paddleocr.ai/latest/version3.x/algorithm/PaddleOCR-VL/PaddleOCR-VL.html).
+
+ - **Características principales**:
+ - **Arquitectura VLM compacta pero potente**: Presentamos un novedoso modelo de visión y lenguaje diseñado específicamente para una inferencia eficiente en recursos, logrando un rendimiento sobresaliente en el reconocimiento de elementos. Al integrar un codificador visual dinámico de alta resolución al estilo NaViT con el modelo de lenguaje ligero ERNIE-4.5-0.3B, mejoramos significativamente las capacidades de reconocimiento y la eficiencia de decodificación del modelo. Esta integración mantiene una alta precisión mientras reduce las demandas computacionales, lo que lo hace adecuado para aplicaciones de procesamiento de documentos eficientes y prácticas.
+ - **Rendimiento SOTA en análisis de documentos**: PaddleOCR-VL logra un rendimiento de vanguardia tanto en el análisis de documentos a nivel de página como en el reconocimiento a nivel de elemento. Supera significativamente a las soluciones basadas en pipeline existentes y exhibe una fuerte competitividad frente a los modelos de visión y lenguaje (VLM) líderes en el análisis de documentos. Además, sobresale en el reconocimiento de elementos de documentos complejos, como texto, tablas, fórmulas y gráficos, lo que lo hace adecuado para una amplia gama de tipos de contenido desafiantes, incluyendo texto manuscrito y documentos históricos. Esto lo hace altamente versátil y adecuado para una amplia gama de tipos de documentos y escenarios.
+ - **Soporte multilingüe**: PaddleOCR-VL admite 109 idiomas, cubriendo los principales idiomas globales, incluyendo, entre otros, chino, inglés, japonés, latín y coreano, así como idiomas con diferentes escrituras y estructuras, como el ruso (escritura cirílica), el árabe, el hindi (escritura devanagari) y el tailandés. Esta amplia cobertura de idiomas mejora sustancialmente la aplicabilidad de nuestro sistema a escenarios de procesamiento de documentos multilingües y globalizados.
+
+- Lanzamiento del modelo de reconocimiento multilingüe PP-OCRv5:
+ - Se mejoró la precisión y cobertura del reconocimiento de escritura latina; se añadió compatibilidad con sistemas de escritura cirílico, árabe, devanagari, telugu, tamil y otros, cubriendo el reconocimiento de 109 idiomas. El modelo tiene solo 2M de parámetros, y la precisión de algunos modelos ha aumentado más de un 40% en comparación con la generación anterior.
+
+
+
+
+
+2025.08.21: Lanzamiento de PaddleOCR 3.2.0
+
+- **Adiciones significativas de modelos:**
+ - Se introdujeron entrenamiento, inferencia y despliegue para modelos de reconocimiento PP-OCRv5 en inglés, tailandés y griego. **El modelo PP-OCRv5 en inglés ofrece una mejora del 11% en escenarios en inglés en comparación con el modelo principal PP-OCRv5, con los modelos de reconocimiento en tailandés y griego alcanzando precisiones del 82,68% y 89,28%, respectivamente.**
+
+- **Mejoras en las capacidades de despliegue:**
+ - **Compatibilidad total con las versiones 3.1.0 y 3.1.1 del framework PaddlePaddle.**
+ - **Actualización integral de la solución de despliegue local en C++ de PP-OCRv5, que ahora admite tanto Linux como Windows, con paridad de características y precisión idéntica a la implementación en Python.**
+ - **La inferencia de alto rendimiento ahora admite CUDA 12, y la inferencia puede realizarse utilizando los backends Paddle Inference u ONNX Runtime.**
+ - **La solución de despliegue orientado a servicios de alta estabilidad ahora es completamente de código abierto, lo que permite a los usuarios personalizar imágenes Docker y SDKs según sea necesario.**
+ - La solución de despliegue orientado a servicios de alta estabilidad también admite la invocación mediante solicitudes HTTP construidas manualmente, lo que permite el desarrollo de código del lado del cliente en cualquier lenguaje de programación.
+
+- **Soporte de benchmarks:**
+ - **Todas las líneas de producción ahora admiten benchmarking detallado, permitiendo medir el tiempo de inferencia de extremo a extremo, así como datos de latencia por capa y por módulo para ayudar en el análisis de rendimiento. [Aquí](docs/version3.x/pipeline_usage/instructions/benchmark.en.md) se explica cómo configurar y usar la función de benchmark.**
+ - **La documentación se ha actualizado para incluir métricas clave para configuraciones de uso común en hardware convencional, como la latencia de inferencia y el uso de memoria, proporcionando referencias de despliegue para los usuarios.**
+
+- **Corrección de errores:**
+ - Se resolvió el problema del guardado fallido de registros durante el entrenamiento del modelo.
+ - Se actualizó el componente de aumento de datos para modelos de fórmulas para compatibilidad con versiones más recientes de la dependencia albumentations, y se corrigieron advertencias de bloqueo al usar el paquete tokenizers en escenarios multiproceso.
+ - Se corrigieron inconsistencias en los comportamientos de los interruptores (p. ej., `use_chart_parsing`) en los archivos de configuración de PP-StructureV3 en comparación con otros pipelines.
+
+- **Otras mejoras:**
+ - **Se separaron las dependencias principales y opcionales. Solo se requieren dependencias principales mínimas para el reconocimiento de texto básico; las dependencias adicionales para el análisis de documentos y la extracción de información se pueden instalar según sea necesario.**
+ - **Se habilitó la compatibilidad con tarjetas gráficas NVIDIA RTX de la serie 50 en Windows; los usuarios pueden consultar la [guía de instalación](docs/version3.x/installation.en.md) para conocer las versiones correspondientes del framework PaddlePaddle.**
+ - **Los modelos de la serie PP-OCR ahora admiten la devolución de coordenadas de caracteres individuales.**
+ - Se añadieron fuentes de descarga de modelos de AIStudio, ModelScope y otras, permitiendo a los usuarios especificar la fuente para las descargas de modelos.
+ - Se añadió compatibilidad con la conversión de gráficos a tablas a través del módulo PP-Chart2Table.
+ - Se optimizaron las descripciones de la documentación para mejorar la usabilidad.
+
+
+
+[Historial de cambios](https://paddlepaddle.github.io/PaddleOCR/latest/en/update/update.html)
+
+
+## 🚀 Inicio rápido
+
+### Paso 1: Pruébalo en línea
+El sitio web oficial de PaddleOCR ofrece un **Centro de experiencia** interactivo y **APIs** — sin necesidad de configuración, solo un clic para experimentar.
+
+👉 [Visitar el sitio web oficial](https://www.paddleocr.com)
+
+### Paso 2: Despliegue local
+Para uso local, consulte la siguiente documentación según sus necesidades:
+
+- **Serie PP-OCR**: Consulte la [Documentación de PP-OCR](https://www.paddleocr.ai/latest/en/version3.x/pipeline_usage/OCR.html)
+- **Serie PaddleOCR-VL**: Consulte la [Documentación de PaddleOCR-VL](https://www.paddleocr.ai/latest/en/version3.x/pipeline_usage/PaddleOCR-VL.html)
+- **PP-StructureV3**: Consulte la [Documentación de PP-StructureV3](https://www.paddleocr.ai/latest/en/version3.x/pipeline_usage/PP-StructureV3.html)
+- **Más capacidades**: Consulte la [Documentación de más capacidades](https://www.paddleocr.ai/latest/en/version3.x/pipeline_usage/pipeline_overview.html)
+
+
+## 🧩 Más características
+
+- Convertir modelos al formato ONNX: [Obtención de modelos ONNX](https://paddlepaddle.github.io/PaddleOCR/latest/en/version3.x/inference_deployment/others/obtaining_onnx_models.html).
+- Acelerar la inferencia usando motores como OpenVINO, ONNX Runtime, TensorRT, o realizar inferencia usando modelos en formato ONNX: [Inferencia de alto rendimiento](https://paddlepaddle.github.io/PaddleOCR/latest/en/version3.x/inference_deployment/local_inference/high_performance_inference.html).
+- Acelerar la inferencia usando múltiples GPU y múltiples procesos: [Inferencia paralela para pipelines](https://paddlepaddle.github.io/PaddleOCR/latest/en/version3.x/pipeline_usage/instructions/parallel_inference.html).
+- Integrar PaddleOCR en aplicaciones escritas en C++, C#, Java, etc.: [Serving](https://paddlepaddle.github.io/PaddleOCR/latest/en/version3.x/inference_deployment/serving/serving.html).
+
+## 🔄 Resumen rápido de los resultados de ejecución
+
+### PP-OCRv5
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+| Cuenta oficial de PaddlePaddle en WeChat | Únete al grupo de discusión técnica |
+| :---: | :---: |
+|
|
|
+
+
+| Nombre del proyecto | Descripción |
+| ------------ | ----------- |
+| [Dify](https://github.com/langgenius/dify)
|Plataforma lista para producción para el desarrollo de flujos de trabajo agénticos.|
+| [RAGFlow](https://github.com/infiniflow/ragflow)
|Motor RAG basado en la comprensión profunda de documentos.|
+| [pathway](https://github.com/pathwaycom/pathway)
|Framework ETL de Python para procesamiento de flujos, análisis en tiempo real, pipelines de LLM y RAG.|
+| [MinerU](https://github.com/opendatalab/MinerU)
|Herramienta de conversión de documentos de múltiples tipos a Markdown.|
+| [Umi-OCR](https://github.com/hiroi-sora/Umi-OCR)
|Software de OCR offline por lotes, gratuito y de código abierto.|
+| [cherry-studio](https://github.com/CherryHQ/cherry-studio)
|Cliente de escritorio compatible con múltiples proveedores de LLM.|
+| [haystack](https://github.com/deepset-ai/haystack)
|Framework de orquestación de IA para construir aplicaciones LLM personalizables y listas para producción.|
+| [OmniParser](https://github.com/microsoft/OmniParser)
|OmniParser: herramienta de análisis de pantalla para agentes GUI basados únicamente en visión.|
+| [QAnything](https://github.com/netease-youdao/QAnything)
|Preguntas y respuestas basadas en cualquier cosa.|
+| [Ver más proyectos](./awesome_projects.md) | [Más proyectos basados en PaddleOCR](./awesome_projects.md)|
+
+
+
+
+
+
+
+
+
+
+
+
Boîte à outils OCR de pointe mondiale & Moteur d'IA documentaire
+
+[English](../README.md) | [简体中文](./README_cn.md) | [繁體中文](./README_tcn.md) | [日本語](./README_ja.md) | [한국어](./README_ko.md) | Français | [Русский](./README_ru.md) | [Español](./README_es.md) | [العربية](./README_ar.md)
+
+
+
+[](https://pepy.tech/projects/paddleocr)
+[](https://github.com/PaddlePaddle/PaddleOCR/network/dependents)
+
+
+
+
+[](https://www.paddleocr.com)
+[](https://deepwiki.com/PaddlePaddle/PaddleOCR)
+[](../LICENSE)
+
+
+
+
+
+
+2026.05.28 : Publication de PaddleOCR 3.6.0
+
+- Points forts de PaddleOCR-VL-1.6 :
+
+ - **Nouvelle précision SOTA** : 96.3% sur OmniDocBench v1.6, nouveau SOTA sur OmniDocBench v1.5 et Real5-OmniDocBench.
+ - **Amélioration complète** : améliorations significatives des tableaux, documents anciens et caractères rares.
+ - **Migration transparente** : architecture entièrement compatible avec PaddleOCR-VL-1.5.
+ - **Essayez** : [HuggingFace](https://huggingface.co/PaddlePaddle/PaddleOCR-VL-1.6) ou [site officiel](https://www.paddleocr.com).
+
+
+
+2026.04.21 : Publication de PaddleOCR 3.5.0
+
+* **Backends d'inférence plus flexibles** : basculez en toute transparence entre les graphes statiques Paddle, les graphes dynamiques Paddle et Transformers. PaddleOCR est désormais profondément intégré à l'écosystème Hugging Face, et 20 modèles majeurs prennent en charge Transformers comme backend d'inférence.
+* **Conversion des documents bureautiques en Markdown** : conversion des formats courants comme Word, Excel et PowerPoint vers Markdown.
+* **Export DOCX des résultats d'analyse** : les séries `PaddleOCR-VL`, `PP-StructureV3` et `PP-DocTranslation` prennent désormais en charge l'export des résultats d'analyse au format DOCX pour une consultation et une édition pratiques dans Microsoft Word.
+* **SDK officiel d'inférence dans le navigateur** : sortie du SDK officiel d'inférence dans le navigateur `PaddleOCR.js`, qui permet d'exécuter `PP-OCRv5` directement dans le navigateur.
+
+
+
+
+2026.01.29 : Publication de PaddleOCR 3.4.0
+* PaddleOCR-VL-1.5 (VLM 0,9 milliard de paramètres, état de l'art) : Notre dernier modèle phare pour l'analyse de documents est désormais disponible !
+ * **94,5 % de précision sur OmniDocBench** : Surpasse les grands modèles généralistes de premier rang et les analyseurs de documents spécialisés.
+ * **Robustesse dans le monde réel** : Premier à introduire l'algorithme **PP-DocLayoutV3** pour le positionnement de formes irrégulières, maîtrisant 5 scénarios difficiles : *Inclinaison, Déformation, Numérisation, Éclairage et Photographie d'écran*.
+ * **Extension des capacités** : Prend désormais en charge la **Reconnaissance de sceaux**, la **Détection de texte**, et s'étend à **111 langues** (incluant le tibétain et le bengali).
+ * **Maîtrise des longs documents** : Prend en charge la fusion automatique de tableaux sur plusieurs pages et l'identification hiérarchique des titres.
+ * **Essayez-le maintenant** : Disponible sur [HuggingFace](https://huggingface.co/PaddlePaddle/PaddleOCR-VL-1.5) ou sur notre [Site officiel](https://www.paddleocr.com).
+
+
+
+
+2025.10.16 : Publication de PaddleOCR 3.3.0
+
+- Publication de PaddleOCR-VL :
+ - **Présentation du modèle** :
+ - **PaddleOCR-VL** est un modèle de pointe et économe en ressources, spécialement conçu pour l'analyse de documents. Son composant principal est PaddleOCR-VL-0.9B, un modèle vision-langage (VLM) compact mais puissant qui intègre un encodeur visuel à résolution dynamique de style NaViT avec le modèle de langage ERNIE-4.5-0.3B pour permettre une reconnaissance précise des éléments. **Ce modèle innovant prend en charge efficacement 109 langues et excelle dans la reconnaissance d'éléments complexes (par exemple, texte, tableaux, formules et graphiques), tout en maintenant une consommation minimale de ressources**. Grâce à des évaluations complètes sur des benchmarks publics largement utilisés et des benchmarks internes, PaddleOCR-VL atteint des performances de pointe à la fois dans l'analyse de documents au niveau de la page et dans la reconnaissance au niveau des éléments. Il surpasse significativement les solutions existantes, présente une forte compétitivité face aux VLM de premier plan, et offre des vitesses d'inférence rapides. Ces atouts le rendent très adapté au déploiement pratique dans des scénarios du monde réel. Le modèle a été publié sur [HuggingFace](https://huggingface.co/PaddlePaddle/PaddleOCR-VL). Tout le monde est invité à le télécharger et à l'utiliser ! Plus d'informations d'introduction sont disponibles dans [PaddleOCR-VL](https://www.paddleocr.ai/latest/version3.x/algorithm/PaddleOCR-VL/PaddleOCR-VL.html).
+
+ - **Fonctionnalités principales** :
+ - **Architecture VLM compacte mais puissante** : Nous présentons un nouveau modèle vision-langage spécialement conçu pour une inférence économe en ressources, atteignant des performances remarquables dans la reconnaissance d'éléments. En intégrant un encodeur visuel haute résolution dynamique de style NaViT avec le modèle de langage léger ERNIE-4.5-0.3B, nous améliorons considérablement les capacités de reconnaissance et l'efficacité du décodage du modèle. Cette intégration maintient une haute précision tout en réduisant les besoins de calcul, ce qui le rend bien adapté aux applications de traitement de documents efficaces et pratiques.
+ - **Performances de pointe en analyse de documents** : PaddleOCR-VL atteint des performances à l'état de l'art à la fois dans l'analyse de documents au niveau de la page et dans la reconnaissance au niveau des éléments. Il surpasse significativement les solutions existantes basées sur des pipelines et présente une forte compétitivité face aux principaux modèles vision-langage (VLM) en analyse de documents. De plus, il excelle dans la reconnaissance d'éléments documentaires complexes, tels que le texte, les tableaux, les formules et les graphiques, ce qui le rend adapté à une large gamme de types de contenu difficiles, y compris le texte manuscrit et les documents historiques. Cela le rend très polyvalent et adapté à une large gamme de types de documents et de scénarios.
+ - **Support multilingue** : PaddleOCR-VL prend en charge 109 langues, couvrant les principales langues mondiales, notamment le chinois, l'anglais, le japonais, le latin et le coréen, ainsi que les langues avec des scripts et des structures différents, tels que le russe (script cyrillique), l'arabe, l'hindi (script devanagari) et le thaï. Cette large couverture linguistique améliore considérablement l'applicabilité de notre système aux scénarios de traitement de documents multilingues et mondialisés.
+
+- Publication du modèle de reconnaissance multilingue PP-OCRv5 :
+ - Amélioration de la précision et de la couverture de la reconnaissance des scripts latins ; ajout de la prise en charge des systèmes cyrillique, arabe, devanagari, télougou, tamoul et d'autres systèmes linguistiques, couvrant la reconnaissance de 109 langues. Le modèle ne compte que 2 millions de paramètres, et la précision de certains modèles a augmenté de plus de 40 % par rapport à la génération précédente.
+
+
+
+
+
+2025.08.21 : Publication de PaddleOCR 3.2.0
+
+- **Ajouts significatifs de modèles :**
+ - Introduction de l'entraînement, de l'inférence et du déploiement pour les modèles de reconnaissance PP-OCRv5 en anglais, thaï et grec. **Le modèle PP-OCRv5 anglais apporte une amélioration de 11 % dans les scénarios en anglais par rapport au modèle principal PP-OCRv5, avec les modèles de reconnaissance thaï et grec atteignant des précisions de 82,68 % et 89,28 %, respectivement.**
+
+- **Améliorations des capacités de déploiement :**
+ - **Prise en charge complète des versions 3.1.0 et 3.1.1 du framework PaddlePaddle.**
+ - **Mise à niveau complète de la solution de déploiement local C++ de PP-OCRv5, prenant désormais en charge Linux et Windows, avec une parité de fonctionnalités et une précision identique à l'implémentation Python.**
+ - **L'inférence haute performance prend désormais en charge CUDA 12, et l'inférence peut être effectuée en utilisant le backend Paddle Inference ou ONNX Runtime.**
+ - **La solution de déploiement orientée services à haute stabilité est désormais entièrement open-source, permettant aux utilisateurs de personnaliser les images Docker et les SDK selon leurs besoins.**
+ - La solution de déploiement orientée services à haute stabilité prend également en charge l'invocation via des requêtes HTTP construites manuellement, permettant le développement de code client dans n'importe quel langage de programmation.
+
+- **Support des benchmarks :**
+ - **Toutes les lignes de production prennent désormais en charge des benchmarks granulaires, permettant la mesure du temps d'inférence de bout en bout ainsi que les données de latence par couche et par module pour faciliter l'analyse des performances. [Voici](docs/version3.x/pipeline_usage/instructions/benchmark.en.md) comment configurer et utiliser la fonctionnalité de benchmark.**
+ - **La documentation a été mise à jour pour inclure les métriques clés pour les configurations couramment utilisées sur le matériel grand public, telles que la latence d'inférence et l'utilisation de la mémoire, fournissant des références de déploiement pour les utilisateurs.**
+
+- **Corrections de bugs :**
+ - Résolution du problème de l'échec de sauvegarde des journaux lors de l'entraînement du modèle.
+ - Mise à niveau du composant d'augmentation de données pour les modèles de formules pour la compatibilité avec les nouvelles versions de la dépendance albumentations, et correction des avertissements de blocage lors de l'utilisation du package tokenizers dans des scénarios multi-processus.
+ - Correction des incohérences dans les comportements des commutateurs (par exemple, `use_chart_parsing`) dans les fichiers de configuration PP-StructureV3 par rapport aux autres pipelines.
+
+- **Autres améliorations :**
+ - **Séparation des dépendances principales et optionnelles. Seules les dépendances principales minimales sont requises pour la reconnaissance de texte de base ; des dépendances supplémentaires pour l'analyse de documents et l'extraction d'informations peuvent être installées selon les besoins.**
+ - **Activation de la prise en charge des cartes graphiques NVIDIA RTX série 50 sous Windows ; les utilisateurs peuvent consulter le [guide d'installation](docs/version3.x/installation.en.md) pour les versions correspondantes du framework PaddlePaddle.**
+ - **Les modèles de la série PP-OCR prennent désormais en charge le retour des coordonnées de chaque caractère.**
+ - Ajout de sources de téléchargement de modèles AIStudio, ModelScope et autres, permettant aux utilisateurs de spécifier la source pour les téléchargements de modèles.
+ - Ajout de la prise en charge de la conversion graphique en tableau via le module PP-Chart2Table.
+ - Optimisation des descriptions de documentation pour améliorer la facilité d'utilisation.
+
+
+
+[Journal des modifications](https://paddlepaddle.github.io/PaddleOCR/latest/en/update/update.html)
+
+
+## 🚀 Démarrage rapide
+
+### Étape 1 : Essayer en ligne
+Le site officiel de PaddleOCR propose un **Centre d'expérience** interactif et des **API** — aucune configuration requise, un seul clic pour découvrir.
+
+👉 [Visiter le site officiel](https://www.paddleocr.com)
+
+### Étape 2 : Déploiement local
+Pour une utilisation locale, veuillez consulter la documentation suivante en fonction de vos besoins :
+
+- **Série PP-OCR** : Voir la [documentation PP-OCR](https://www.paddleocr.ai/latest/en/version3.x/pipeline_usage/OCR.html)
+- **Série PaddleOCR-VL** : Voir la [documentation PaddleOCR-VL](https://www.paddleocr.ai/latest/en/version3.x/pipeline_usage/PaddleOCR-VL.html)
+- **PP-StructureV3** : Voir la [documentation PP-StructureV3](https://www.paddleocr.ai/latest/en/version3.x/pipeline_usage/PP-StructureV3.html)
+- **Autres capacités** : Voir la [documentation sur les autres capacités](https://www.paddleocr.ai/latest/en/version3.x/pipeline_usage/pipeline_overview.html)
+
+
+## 🧩 Plus de fonctionnalités
+
+- Convertir des modèles au format ONNX : [Obtenir des modèles ONNX](https://paddlepaddle.github.io/PaddleOCR/latest/en/version3.x/inference_deployment/others/obtaining_onnx_models.html).
+- Accélérer l'inférence à l'aide de moteurs tels qu'OpenVINO, ONNX Runtime, TensorRT, ou effectuer une inférence à l'aide de modèles au format ONNX : [Inférence haute performance](https://paddlepaddle.github.io/PaddleOCR/latest/en/version3.x/inference_deployment/local_inference/high_performance_inference.html).
+- Accélérer l'inférence à l'aide de plusieurs GPU et plusieurs processus : [Inférence parallèle pour les pipelines](https://paddlepaddle.github.io/PaddleOCR/latest/en/version3.x/pipeline_usage/instructions/parallel_inference.html).
+- Intégrer PaddleOCR dans des applications écrites en C++, C#, Java, etc. : [Services](https://paddlepaddle.github.io/PaddleOCR/latest/en/version3.x/inference_deployment/serving/serving.html).
+
+## 🔄 Aperçu rapide des résultats d'exécution
+
+### PP-OCRv5
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+| Compte officiel WeChat de PaddlePaddle | Rejoindre le groupe de discussion technique |
+| :---: | :---: |
+|
|
|
+
+
+| Nom du projet | Description |
+| ------------ | ----------- |
+| [Dify](https://github.com/langgenius/dify)
|Plateforme prête pour la production pour le développement de flux de travail agentiques.|
+| [RAGFlow](https://github.com/infiniflow/ragflow)
|Moteur RAG basé sur la compréhension approfondie des documents.|
+| [pathway](https://github.com/pathwaycom/pathway)
|Framework Python ETL pour le traitement de flux, l'analytique en temps réel, les pipelines LLM et le RAG.|
+| [MinerU](https://github.com/opendatalab/MinerU)
|Outil de conversion de documents multi-types en Markdown.|
+| [Umi-OCR](https://github.com/hiroi-sora/Umi-OCR)
|Logiciel OCR hors ligne par lots, gratuit et open-source.|
+| [cherry-studio](https://github.com/CherryHQ/cherry-studio)
|Un client de bureau prenant en charge plusieurs fournisseurs de LLM.|
+| [haystack](https://github.com/deepset-ai/haystack)
|Framework d'orchestration IA pour construire des applications LLM personnalisables et prêtes pour la production.|
+| [OmniParser](https://github.com/microsoft/OmniParser)
|OmniParser : Outil d'analyse d'écran pour agent GUI basé sur la vision pure.|
+| [QAnything](https://github.com/netease-youdao/QAnything)
|Questions et réponses basées sur n'importe quoi.|
+| [En savoir plus sur les projets](./awesome_projects.md) | [Plus de projets basés sur PaddleOCR](./awesome_projects.md)|
+
+
+
+
+
+
+
+
+
+
+
+
世界をリードするOCRツールキット & ドキュメントAIエンジン
+
+[English](../README.md) | [简体中文](./README_cn.md) | [繁體中文](./README_tcn.md) | 日本語 | [한국어](./README_ko.md) | [Français](./README_fr.md) | [Русский](./README_ru.md) | [Español](./README_es.md) | [العربية](./README_ar.md)
+
+
+
+[](https://pepy.tech/projects/paddleocr)
+[](https://github.com/PaddlePaddle/PaddleOCR/network/dependents)
+
+
+
+
+[](https://www.paddleocr.com)
+[](https://deepwiki.com/PaddlePaddle/PaddleOCR)
+[](../LICENSE)
+
+
+
+
+
+
+2026.05.28: PaddleOCR 3.6.0リリース
+
+- PaddleOCR-VL-1.6の主な特徴:
+
+ - **新SOTA精度**: OmniDocBench v1.6で96.3%、OmniDocBench v1.5とReal5-OmniDocBenchでも新SOTA達成。
+ - **総合的な強化**: テーブル、古文書、希少文字の認識が大幅向上。
+ - **シームレスな移行**: PaddleOCR-VL-1.5と完全互換のアーキテクチャ。
+ - **今すぐ試す**: [HuggingFace](https://huggingface.co/PaddlePaddle/PaddleOCR-VL-1.6)または[公式サイト](https://www.paddleocr.com)。
+
+
+
+2026.04.21: PaddleOCR 3.5.0リリース
+
+* **柔軟な推論バックエンド**: Paddleの静的グラフ、動的グラフ、Transformersをシームレスに切り替え可能。Hugging Face エコシステムに深く対応し、主要20モデルがTransformersを推論バックエンドとしてサポート。
+* **Office文書をMarkdownに変換**: Word、Excel、PowerPoint などの一般的な文書形式を Markdown に変換可能。
+* **解析結果の DOCX 出力**: `PaddleOCR-VL` シリーズ、`PP-StructureV3`、`PP-DocTranslation` で、解析結果を DOCX として出力できるようになり、Microsoft Word での閲覧・編集が容易に。
+* **公式ブラウザ推論 SDK**: 公式ブラウザ推論 SDK `PaddleOCR.js` を公開し、ブラウザ上で `PP-OCRv5` を実行可能。
+
+
+
+
+2026.01.29: PaddleOCR 3.4.0リリース
+* PaddleOCR-VL-1.5(最先端の0.9B VLM): ドキュメント解析のための最新フラッグシップモデルが公開されました!
+ * **OmniDocBenchで94.5%の精度**: トップクラスの汎用大規模モデルや専門ドキュメントパーサーを凌駕。
+ * **実環境でのロバスト性**: 非定型形状位置決定のための**PP-DocLayoutV3**アルゴリズムを初めて導入し、*傾き、歪み、スキャン、照明、画面撮影*の5つの困難なシナリオに対応。
+ * **機能拡張**: **印鑑認識**、**テキスト検出**をサポートし、**111言語**(中国のチベット文字やベンガル文字を含む)に対応拡大。
+ * **長文ドキュメントへの対応**: ページをまたがるテーブルの自動結合および階層的な見出し識別をサポート。
+ * **今すぐ試す**: [HuggingFace](https://huggingface.co/PaddlePaddle/PaddleOCR-VL-1.5)または[公式ウェブサイト](https://www.paddleocr.com)で利用可能です。
+
+
+
+
+2025.10.16: PaddleOCR 3.3.0リリース
+
+- PaddleOCR-VLをリリース:
+ - **モデル紹介**:
+ - **PaddleOCR-VL**はドキュメント解析に特化した最先端かつリソース効率の高いモデルです。コアコンポーネントであるPaddleOCR-VL-0.9Bは、NaViTスタイルの動的解像度ビジュアルエンコーダとERNIE-4.5-0.3B言語モデルを統合したコンパクトながらも強力な視覚言語モデル(VLM)であり、正確な要素認識を実現します。**この革新的なモデルは109言語を効率的にサポートし、複雑な要素(テキスト、テーブル、数式、チャートなど)の認識に優れつつ、リソース消費を最小限に抑えます**。広く使用されている公開ベンチマークおよび社内ベンチマークでの包括的な評価を通じて、PaddleOCR-VLはページレベルのドキュメント解析と要素レベルの認識の両方で最先端の性能を達成しています。既存のソリューションを大幅に上回り、トップクラスのVLMに対して高い競争力を示し、高速な推論速度を提供します。これらの強みにより、実世界のシナリオへの実践的なデプロイメントに非常に適しています。モデルは[HuggingFace](https://huggingface.co/PaddlePaddle/PaddleOCR-VL)で公開されています。ぜひダウンロードしてお使いください!詳細情報は[PaddleOCR-VL](https://www.paddleocr.ai/latest/version3.x/algorithm/PaddleOCR-VL/PaddleOCR-VL.html)をご覧ください。
+
+ - **主要機能**:
+ - **コンパクトかつ強力なVLMアーキテクチャ**: リソース効率の高い推論に特化した新しい視覚言語モデルを提案し、要素認識において卓越した性能を実現しました。NaViTスタイルの動的高解像度ビジュアルエンコーダと軽量なERNIE-4.5-0.3B言語モデルを統合することで、モデルの認識能力とデコード効率を大幅に向上させました。この統合により、計算負荷を削減しつつ高い精度を維持し、効率的で実用的なドキュメント処理アプリケーションに適しています。
+ - **ドキュメント解析における最先端性能**: PaddleOCR-VLはページレベルのドキュメント解析と要素レベルの認識の両方で最先端の性能を達成しています。既存のパイプラインベースのソリューションを大幅に上回り、ドキュメント解析における主要な視覚言語モデル(VLM)に対して高い競争力を示しています。さらに、テキスト、テーブル、数式、チャートなどの複雑なドキュメント要素の認識に優れ、手書きテキストや歴史文書を含む幅広い種類のコンテンツに対応可能です。これにより、多様なドキュメントタイプやシナリオに対して高い汎用性を発揮します。
+ - **多言語サポート**: PaddleOCR-VLは109言語をサポートし、中国語、英語、日本語、ラテン語、韓国語をはじめ、ロシア語(キリル文字)、アラビア語、ヒンディー語(デーヴァナーガリー文字)、タイ語など、異なる文字体系や構造を持つ言語を含む主要なグローバル言語をカバーしています。この幅広い言語対応により、多言語およびグローバルなドキュメント処理シナリオへの適用性が大幅に向上しています。
+
+- PP-OCRv5多言語認識モデルをリリース:
+ - ラテン文字認識の精度とカバレッジを改善。キリル文字、アラビア文字、デーヴァナーガリー文字、テルグ文字、タミル文字など他の文字体系のサポートを追加し、109言語の認識をカバー。モデルのパラメータ数はわずか2Mで、一部のモデルの精度は前世代と比較して40%以上向上しています。
+
+
+
+
+
+2025.08.21: PaddleOCR 3.2.0リリース
+
+- **モデルの大幅な追加:**
+ - PP-OCRv5認識モデルの英語、タイ語、ギリシャ語の学習、推論、デプロイメントを導入。**PP-OCRv5英語モデルは、主要なPP-OCRv5モデルと比較して英語シナリオで11%の改善を達成し、タイ語およびギリシャ語の認識モデルはそれぞれ82.68%および89.28%の精度を実現しています。**
+
+- **デプロイメント機能のアップグレード:**
+ - **PaddlePaddleフレームワークバージョン3.1.0および3.1.1を完全サポート。**
+ - **PP-OCRv5 C++ローカルデプロイメントソリューションを全面アップグレードし、LinuxとWindowsの両方をサポート。Python実装と同等の機能および精度を実現。**
+ - **高性能推論がCUDA 12をサポートし、Paddle InferenceまたはONNX Runtimeバックエンドを使用した推論が可能。**
+ - **高安定性サービス指向デプロイメントソリューションが完全にオープンソース化され、ユーザーが必要に応じてDockerイメージやSDKをカスタマイズ可能。**
+ - 高安定性サービス指向デプロイメントソリューションは、手動でHTTPリクエストを構築して呼び出すこともサポートしており、任意のプログラミング言語でクライアント側コードの開発が可能です。
+
+- **ベンチマークサポート:**
+ - **全プロダクションラインがきめ細かいベンチマークをサポートし、エンドツーエンドの推論時間だけでなく、レイヤーごとおよびモジュールごとのレイテンシデータの測定が可能となり、性能分析を支援します。ベンチマーク機能のセットアップと使用方法は[こちら](docs/version3.x/pipeline_usage/instructions/benchmark.en.md)をご覧ください。**
+ - **主要なハードウェアでよく使用される構成の推論レイテンシやメモリ使用量などの重要な指標を含むようドキュメントを更新し、ユーザーにデプロイメントの参考情報を提供。**
+
+- **バグ修正:**
+ - モデル学習時のログ保存失敗の問題を解決。
+ - 数式モデルのデータ拡張コンポーネントをアップグレードし、albumentations依存関係の新しいバージョンとの互換性を確保。マルチプロセスシナリオでtokenizersパッケージ使用時のデッドロック警告を修正。
+ - PP-StructureV3設定ファイルにおけるスイッチ動作(例:`use_chart_parsing`)の他のパイプラインとの不整合を修正。
+
+- **その他の改善:**
+ - **コア依存関係とオプション依存関係を分離。基本的なテキスト認識には最小限のコア依存関係のみが必要で、ドキュメント解析や情報抽出のための追加依存関係は必要に応じてインストール可能。**
+ - **WindowsでNVIDIA RTX 50シリーズグラフィックスカードのサポートを有効化。対応するPaddlePaddleフレームワークバージョンについては[インストールガイド](docs/version3.x/installation.en.md)を参照してください。**
+ - **PP-OCRシリーズモデルが単一文字座標の返却をサポート。**
+ - AIStudio、ModelScopeなどのモデルダウンロードソースを追加し、ユーザーがモデルダウンロードのソースを指定可能に。
+ - PP-Chart2Tableモジュールによるチャートからテーブルへの変換サポートを追加。
+ - ドキュメントの説明を最適化し、使いやすさを向上。
+
+
+
+[更新履歴](https://paddlepaddle.github.io/PaddleOCR/latest/en/update/update.html)
+
+
+## 🚀 クイックスタート
+
+### ステップ1:オンラインで試す
+PaddleOCR公式ウェブサイトでは、インタラクティブな**体験センター**と**API**を提供しています。セットアップ不要、ワンクリックで体験できます。
+
+👉 [公式ウェブサイトへアクセス](https://www.paddleocr.com)
+
+### ステップ2:ローカルデプロイメント
+ローカルでの使用については、ニーズに応じて以下のドキュメントを参照してください:
+
+- **PP-OCRシリーズ**: [PP-OCRドキュメント](https://www.paddleocr.ai/latest/en/version3.x/pipeline_usage/OCR.html)を参照
+- **PaddleOCR-VLシリーズ**: [PaddleOCR-VLドキュメント](https://www.paddleocr.ai/latest/en/version3.x/pipeline_usage/PaddleOCR-VL.html)を参照
+- **PP-StructureV3**: [PP-StructureV3ドキュメント](https://www.paddleocr.ai/latest/en/version3.x/pipeline_usage/PP-StructureV3.html)を参照
+- **その他の機能**: [その他の機能ドキュメント](https://www.paddleocr.ai/latest/en/version3.x/pipeline_usage/pipeline_overview.html)を参照
+
+
+## 🧩 その他の機能
+
+- モデルをONNX形式に変換: [ONNXモデルの取得](https://paddlepaddle.github.io/PaddleOCR/latest/en/version3.x/inference_deployment/others/obtaining_onnx_models.html)
+- OpenVINO、ONNX Runtime、TensorRTなどのエンジンを使用した推論高速化、またはONNX形式モデルによる推論: [高性能推論](https://paddlepaddle.github.io/PaddleOCR/latest/en/version3.x/inference_deployment/local_inference/high_performance_inference.html)
+- マルチGPUおよびマルチプロセスによる推論高速化: [パイプラインの並列推論](https://paddlepaddle.github.io/PaddleOCR/latest/en/version3.x/pipeline_usage/instructions/parallel_inference.html)
+- PaddleOCRをC++、C#、Javaなどで書かれたアプリケーションに統合: [サービスデプロイメント](https://paddlepaddle.github.io/PaddleOCR/latest/en/version3.x/inference_deployment/serving/serving.html)
+
+## 🔄 実行結果の概要
+
+### PP-OCRv5
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+| PaddlePaddle WeChat公式アカウント | 技術ディスカッショングループに参加 |
+| :---: | :---: |
+|
|
|
+
+
+| プロジェクト名 | 説明 |
+| ------------ | ----------- |
+| [Dify](https://github.com/langgenius/dify)
|エージェントワークフロー開発のためのプロダクション対応プラットフォーム。|
+| [RAGFlow](https://github.com/infiniflow/ragflow)
|深いドキュメント理解に基づくRAGエンジン。|
+| [pathway](https://github.com/pathwaycom/pathway)
|ストリーム処理、リアルタイム分析、LLMパイプライン、RAG向けのPython ETLフレームワーク。|
+| [MinerU](https://github.com/opendatalab/MinerU)
|マルチタイプドキュメントからMarkdownへの変換ツール。|
+| [Umi-OCR](https://github.com/hiroi-sora/Umi-OCR)
|無料・オープンソースのバッチオフラインOCRソフトウェア。|
+| [cherry-studio](https://github.com/CherryHQ/cherry-studio)
|複数のLLMプロバイダーをサポートするデスクトップクライアント。|
+| [haystack](https://github.com/deepset-ai/haystack)
|カスタマイズ可能なプロダクション対応LLMアプリケーションを構築するためのAIオーケストレーションフレームワーク。|
+| [OmniParser](https://github.com/microsoft/OmniParser)
|純粋なビジョンベースのGUIエージェント向け画面解析ツール。|
+| [QAnything](https://github.com/netease-youdao/QAnything)
|あらゆるものに基づく質問応答。|
+| [その他のプロジェクトを見る](./awesome_projects.md) | [PaddleOCRに基づくその他のプロジェクト](./awesome_projects.md)|
+
+
+
+
+
+
+
+
+
+
+
+
세계 최고의 OCR 툴킷 & 문서 AI 엔진
+
+[English](../README.md) | [简体中文](./README_cn.md) | [繁體中文](./README_tcn.md) | [日本語](./README_ja.md) | 한국어 | [Français](./README_fr.md) | [Русский](./README_ru.md) | [Español](./README_es.md) | [العربية](./README_ar.md)
+
+
+
+[](https://pepy.tech/projects/paddleocr)
+[](https://github.com/PaddlePaddle/PaddleOCR/network/dependents)
+
+
+
+
+[](https://www.paddleocr.com)
+[](https://deepwiki.com/PaddlePaddle/PaddleOCR)
+[](../LICENSE)
+
+
+
+
+
+
+2026.05.28: PaddleOCR 3.6.0 출시
+
+- PaddleOCR-VL-1.6 주요 특징:
+
+ - **새로운 SOTA 정확도**: OmniDocBench v1.6에서 96.3%, OmniDocBench v1.5 및 Real5-OmniDocBench에서도 새로운 SOTA.
+ - **종합 강화**: 테이블, 고문서, 희귀 문자 인식 대폭 향상.
+ - **원활한 마이그레이션**: PaddleOCR-VL-1.5와 완전 호환 아키텍처.
+ - **지금 사용해보기**: [HuggingFace](https://huggingface.co/PaddlePaddle/PaddleOCR-VL-1.6) 또는 [공식 사이트](https://www.paddleocr.com).
+
+
+
+2026.04.21: PaddleOCR 3.5.0 출시
+
+* **유연한 추론 백엔드 전환**: Paddle 정적 그래프, Paddle 동적 그래프, Transformers 사이를 원활하게 전환할 수 있습니다. Hugging Face 생태계에 깊이 통합되었으며, 주요 20개 모델이 Transformers를 추론 백엔드로 지원합니다.
+* **Office 문서를 Markdown으로 변환**: Word, Excel, PowerPoint 등 일반적인 문서 형식을 Markdown으로 변환할 수 있습니다.
+* **분석 결과 DOCX 내보내기**: `PaddleOCR-VL` 시리즈, `PP-StructureV3`, `PP-DocTranslation`이 이제 분석 결과를 DOCX로 내보내 Microsoft Word에서 편리하게 확인하고 편집할 수 있습니다.
+* **공식 브라우저 추론 SDK**: 공식 브라우저 추론 SDK `PaddleOCR.js`를 출시하여 브라우저에서 `PP-OCRv5`를 실행할 수 있습니다.
+
+
+
+
+2026.01.29: PaddleOCR 3.4.0 출시
+* PaddleOCR-VL-1.5 (최첨단 0.9B VLM): 문서 파싱을 위한 최신 플래그십 모델이 출시되었습니다!
+ * **OmniDocBench에서 94.5% 정확도**: 최상위 범용 대규모 모델 및 전문 문서 파서를 능가합니다.
+ * **실제 환경 강건성**: 비정형 형태 위치 지정을 위한 **PP-DocLayoutV3** 알고리즘을 최초 도입하여 *기울기, 왜곡, 스캔, 조명, 화면 촬영*이라는 5가지 까다로운 시나리오를 정복합니다.
+ * **기능 확장**: **인감 인식**, **텍스트 탐지**를 지원하며, **111개 언어**(중국 티베트 문자 및 벵골어 포함)로 확장되었습니다.
+ * **장문서 처리**: 자동 교차 페이지 표 병합 및 계층적 제목 식별을 지원합니다.
+ * **지금 사용해 보세요**: [HuggingFace](https://huggingface.co/PaddlePaddle/PaddleOCR-VL-1.5) 또는 [공식 웹사이트](https://www.paddleocr.com)에서 이용 가능합니다.
+
+
+
+
+2025.10.16: PaddleOCR 3.3.0 출시
+
+- PaddleOCR-VL 출시:
+ - **모델 소개**:
+ - **PaddleOCR-VL**은 문서 파싱에 특화된 최첨단 자원 효율적 모델입니다. 핵심 구성 요소인 PaddleOCR-VL-0.9B는 NaViT 스타일의 동적 해상도 비주얼 인코더와 ERNIE-4.5-0.3B 언어 모델을 통합하여 정확한 요소 인식을 가능하게 하는 컴팩트하면서도 강력한 비전-언어 모델(VLM)입니다. **이 혁신적인 모델은 109개 언어를 효율적으로 지원하며, 최소한의 자원 소비를 유지하면서 복잡한 요소(텍스트, 표, 수식, 차트 등) 인식에 탁월합니다**. 널리 사용되는 공개 벤치마크와 자체 벤치마크를 통한 종합 평가에서 PaddleOCR-VL은 페이지 수준 문서 파싱과 요소 수준 인식 모두에서 최첨단 성능을 달성합니다. 기존 솔루션을 크게 능가하고, 최상위 VLM과의 경쟁에서도 강한 경쟁력을 보이며, 빠른 추론 속도를 제공합니다. 이러한 강점은 실제 시나리오에서의 실용적 배포에 매우 적합합니다. 모델은 [HuggingFace](https://huggingface.co/PaddlePaddle/PaddleOCR-VL)에 공개되었습니다. 누구나 다운로드하여 사용할 수 있습니다! 더 자세한 소개는 [PaddleOCR-VL](https://www.paddleocr.ai/latest/version3.x/algorithm/PaddleOCR-VL/PaddleOCR-VL.html)에서 확인할 수 있습니다.
+
+ - **핵심 기능**:
+ - **컴팩트하면서도 강력한 VLM 아키텍처**: 자원 효율적 추론에 특화 설계된 새로운 비전-언어 모델을 제시하며, 요소 인식에서 탁월한 성능을 달성합니다. NaViT 스타일의 동적 고해상도 비주얼 인코더와 경량 ERNIE-4.5-0.3B 언어 모델을 통합하여 모델의 인식 능력과 디코딩 효율성을 크게 향상시킵니다. 이러한 통합은 높은 정확도를 유지하면서 연산 요구량을 줄여 효율적이고 실용적인 문서 처리 애플리케이션에 적합합니다.
+ - **문서 파싱 최첨단 성능**: PaddleOCR-VL은 페이지 수준 문서 파싱과 요소 수준 인식 모두에서 최첨단 성능을 달성합니다. 기존 파이프라인 기반 솔루션을 크게 능가하며, 문서 파싱에서 선도적인 비전-언어 모델(VLM)과 강한 경쟁력을 보입니다. 또한 텍스트, 표, 수식, 차트 등 복잡한 문서 요소 인식에 탁월하여 필기체 텍스트 및 역사 문서를 포함한 다양하고 까다로운 콘텐츠 유형에 적합합니다. 이로 인해 다양한 문서 유형과 시나리오에 폭넓게 활용할 수 있습니다.
+ - **다국어 지원**: PaddleOCR-VL은 109개 언어를 지원하며, 중국어, 영어, 일본어, 라틴어, 한국어를 포함한(이에 국한되지 않는) 주요 글로벌 언어와 러시아어(키릴 문자), 아랍어, 힌디어(데바나가리 문자), 태국어 등 다양한 문자 체계와 구조를 가진 언어를 포괄합니다. 이러한 광범위한 언어 지원은 다국어 및 글로벌 문서 처리 시나리오에서의 시스템 적용성을 크게 향상시킵니다.
+
+- PP-OCRv5 다국어 인식 모델 출시:
+ - 라틴 문자 인식의 정확도와 범위를 개선하였습니다. 키릴 문자, 아랍 문자, 데바나가리 문자, 텔루구 문자, 타밀 문자 및 기타 언어 체계 지원을 추가하여 109개 언어 인식을 지원합니다. 모델 파라미터는 2M에 불과하며, 일부 모델의 정확도는 이전 세대 대비 40% 이상 향상되었습니다.
+
+
+
+
+
+2025.08.21: PaddleOCR 3.2.0 출시
+
+- **주요 모델 추가:**
+ - PP-OCRv5 인식 모델의 영어, 태국어, 그리스어 학습, 추론 및 배포를 도입하였습니다. **PP-OCRv5 영어 모델은 기존 PP-OCRv5 메인 모델 대비 영어 시나리오에서 11% 향상을 달성했으며, 태국어 및 그리스어 인식 모델은 각각 82.68%와 89.28%의 정확도를 기록하였습니다.**
+
+- **배포 기능 업그레이드:**
+ - **PaddlePaddle 프레임워크 버전 3.1.0 및 3.1.1 완전 지원.**
+ - **PP-OCRv5 C++ 로컬 배포 솔루션 종합 업그레이드, Linux 및 Windows 모두 지원하며 Python 구현과 동일한 기능 및 정확도를 제공합니다.**
+ - **고성능 추론이 CUDA 12를 지원하며, Paddle Inference 또는 ONNX Runtime 백엔드를 사용하여 추론을 수행할 수 있습니다.**
+ - **고안정성 서비스 지향 배포 솔루션이 완전히 오픈소스화되어, 사용자가 필요에 따라 Docker 이미지와 SDK를 커스터마이징할 수 있습니다.**
+ - 고안정성 서비스 지향 배포 솔루션은 수동으로 구성한 HTTP 요청을 통한 호출도 지원하여, 모든 프로그래밍 언어에서 클라이언트 측 코드 개발이 가능합니다.
+
+- **벤치마크 지원:**
+ - **모든 프로덕션 라인이 세분화된 벤치마킹을 지원하여, 엔드투엔드 추론 시간은 물론 레이어별 및 모듈별 지연 시간 데이터를 측정하여 성능 분석을 지원합니다. 벤치마크 기능의 설정 및 사용 방법은 [여기](docs/version3.x/pipeline_usage/instructions/benchmark.en.md)를 참조하세요.**
+ - **문서에 주류 하드웨어에서의 일반 구성에 대한 주요 지표(추론 지연 시간 및 메모리 사용량 등)가 업데이트되어, 사용자에게 배포 참고 자료를 제공합니다.**
+
+- **버그 수정:**
+ - 모델 학습 중 로그 저장 실패 문제를 해결하였습니다.
+ - 수식 모델의 데이터 증강 구성 요소를 업그레이드하여 최신 버전의 albumentations 종속성과의 호환성을 확보하고, 멀티프로세스 시나리오에서 tokenizers 패키지 사용 시 발생하는 데드락 경고를 수정하였습니다.
+ - PP-StructureV3 구성 파일에서 스위치 동작(예: `use_chart_parsing`)이 다른 파이프라인과 불일치하는 문제를 수정하였습니다.
+
+- **기타 개선 사항:**
+ - **핵심 종속성과 선택적 종속성을 분리하였습니다. 기본 텍스트 인식에는 최소한의 핵심 종속성만 필요하며, 문서 파싱 및 정보 추출을 위한 추가 종속성은 필요에 따라 설치할 수 있습니다.**
+ - **Windows에서 NVIDIA RTX 50 시리즈 그래픽 카드 지원을 활성화하였습니다. 해당 PaddlePaddle 프레임워크 버전은 [설치 가이드](docs/version3.x/installation.en.md)를 참조하세요.**
+ - **PP-OCR 시리즈 모델이 단일 문자 좌표 반환을 지원합니다.**
+ - AIStudio, ModelScope 등 모델 다운로드 소스를 추가하여, 사용자가 모델 다운로드 소스를 지정할 수 있습니다.
+ - PP-Chart2Table 모듈을 통한 차트-표 변환 지원을 추가하였습니다.
+ - 사용성 향상을 위해 문서 설명을 최적화하였습니다.
+
+
+
+[변경 이력](https://paddlepaddle.github.io/PaddleOCR/latest/en/update/update.html)
+
+
+## 🚀 빠른 시작
+
+### 1단계: 온라인 체험
+PaddleOCR 공식 웹사이트에서는 별도 설정 없이 클릭 한 번으로 체험할 수 있는 인터랙티브 **체험 센터**와 **API**를 제공합니다.
+
+👉 [공식 웹사이트 방문](https://www.paddleocr.com)
+
+### 2단계: 로컬 배포
+로컬 사용을 위해 필요에 따라 다음 문서를 참조하세요:
+
+- **PP-OCR 시리즈**: [PP-OCR 문서](https://www.paddleocr.ai/latest/en/version3.x/pipeline_usage/OCR.html) 참조
+- **PaddleOCR-VL 시리즈**: [PaddleOCR-VL 문서](https://www.paddleocr.ai/latest/en/version3.x/pipeline_usage/PaddleOCR-VL.html) 참조
+- **PP-StructureV3**: [PP-StructureV3 문서](https://www.paddleocr.ai/latest/en/version3.x/pipeline_usage/PP-StructureV3.html) 참조
+- **추가 기능**: [추가 기능 문서](https://www.paddleocr.ai/latest/en/version3.x/pipeline_usage/pipeline_overview.html) 참조
+
+
+## 🧩 추가 기능
+
+- 모델을 ONNX 형식으로 변환: [ONNX 모델 획득](https://paddlepaddle.github.io/PaddleOCR/latest/en/version3.x/inference_deployment/others/obtaining_onnx_models.html).
+- OpenVINO, ONNX Runtime, TensorRT 등의 엔진을 사용한 추론 가속 또는 ONNX 형식 모델을 사용한 추론: [고성능 추론](https://paddlepaddle.github.io/PaddleOCR/latest/en/version3.x/inference_deployment/local_inference/high_performance_inference.html).
+- 다중 GPU 및 다중 프로세스를 사용한 추론 가속: [파이프라인 병렬 추론](https://paddlepaddle.github.io/PaddleOCR/latest/en/version3.x/pipeline_usage/instructions/parallel_inference.html).
+- PaddleOCR를 C++, C#, Java 등으로 작성된 애플리케이션에 통합: [서빙](https://paddlepaddle.github.io/PaddleOCR/latest/en/version3.x/inference_deployment/serving/serving.html).
+
+## 🔄 실행 결과 빠른 미리보기
+
+### PP-OCRv5
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+| PaddlePaddle 위챗 공식 계정 | 기술 토론 그룹 참여 |
+| :---: | :---: |
+|
|
|
+
+
+| 프로젝트 이름 | 설명 |
+| ------------ | ----------- |
+| [Dify](https://github.com/langgenius/dify)
|에이전트 워크플로우 개발을 위한 프로덕션 지원 플랫폼.|
+| [RAGFlow](https://github.com/infiniflow/ragflow)
|심층 문서 이해 기반 RAG 엔진.|
+| [pathway](https://github.com/pathwaycom/pathway)
|스트림 처리, 실시간 분석, LLM 파이프라인 및 RAG를 위한 Python ETL 프레임워크.|
+| [MinerU](https://github.com/opendatalab/MinerU)
|다양한 유형의 문서를 Markdown으로 변환하는 도구.|
+| [Umi-OCR](https://github.com/hiroi-sora/Umi-OCR)
|무료, 오픈소스, 일괄 오프라인 OCR 소프트웨어.|
+| [cherry-studio](https://github.com/CherryHQ/cherry-studio)
|여러 LLM 제공업체를 지원하는 데스크톱 클라이언트.|
+| [haystack](https://github.com/deepset-ai/haystack)
|커스터마이징 가능한 프로덕션 지원 LLM 애플리케이션 구축을 위한 AI 오케스트레이션 프레임워크.|
+| [OmniParser](https://github.com/microsoft/OmniParser)
|순수 비전 기반 GUI 에이전트를 위한 화면 파싱 도구.|
+| [QAnything](https://github.com/netease-youdao/QAnything)
|모든 것에 기반한 질의응답.|
+| [더 많은 프로젝트 보기](./awesome_projects.md) | [PaddleOCR 기반 추가 프로젝트](./awesome_projects.md)|
+
+
+
+
+
+
+
+
+
+
+
+
Ведущий в мире инструментарий OCR и движок Document AI
+
+[English](../README.md) | [简体中文](./README_cn.md) | [繁體中文](./README_tcn.md) | [日本語](./README_ja.md) | [한국어](./README_ko.md) | [Français](./README_fr.md) | Русский | [Español](./README_es.md) | [العربية](./README_ar.md)
+
+
+
+[](https://pepy.tech/projects/paddleocr)
+[](https://github.com/PaddlePaddle/PaddleOCR/network/dependents)
+
+
+
+
+[](https://www.paddleocr.com)
+[](https://deepwiki.com/PaddlePaddle/PaddleOCR)
+[](../LICENSE)
+
+
+
+
+
+
+2026.05.28: Выпуск PaddleOCR 3.6.0
+
+- Ключевые особенности PaddleOCR-VL-1.6:
+
+ - **Новая точность SOTA**: 96.3% на OmniDocBench v1.6, новый SOTA на OmniDocBench v1.5 и Real5-OmniDocBench.
+ - **Всестороннее улучшение**: значительные улучшения в таблицах, древних документах и редких символах.
+ - **Бесшовная миграция**: архитектура полностью совместима с PaddleOCR-VL-1.5.
+ - **Попробуйте**: доступно на [HuggingFace](https://huggingface.co/PaddlePaddle/PaddleOCR-VL-1.6) или [официальном сайте](https://www.paddleocr.com).
+
+
+
+2026.04.21: Выпуск PaddleOCR 3.5.0
+
+* **Гибкое переключение бэкендов инференса**: поддерживается бесшовное переключение между статическим графом Paddle, динамическим графом Paddle и Transformers. PaddleOCR теперь глубоко интегрирован с экосистемой Hugging Face, а 20 ключевых моделей поддерживают Transformers в качестве бэкенда инференса.
+* **Преобразование офисных документов в Markdown**: поддерживается преобразование распространённых форматов документов, таких как Word, Excel и PowerPoint, в Markdown.
+* **Экспорт результатов разбора в DOCX**: серии `PaddleOCR-VL`, `PP-StructureV3` и `PP-DocTranslation` теперь поддерживают экспорт результатов разбора в формат DOCX для удобного просмотра и редактирования в Microsoft Word.
+* **Официальный браузерный SDK инференса**: выпущен официальный браузерный SDK инференса `PaddleOCR.js`, который поддерживает запуск `PP-OCRv5` прямо в браузере.
+
+
+
+
+2026.01.29: Выпуск PaddleOCR 3.4.0
+* PaddleOCR-VL-1.5 (SOTA 0.9B VLM): Наша новейшая флагманская модель для разбора документов уже доступна!
+ * **94,5% точность на OmniDocBench**: Превосходит ведущие универсальные большие модели и специализированные парсеры документов.
+ * **Устойчивость к реальным условиям**: Первая реализация алгоритма **PP-DocLayoutV3** для позиционирования нестандартных форм, освоившая 5 сложных сценариев: *перекос, деформация, сканирование, неравномерное освещение и фотосъёмка экрана*.
+ * **Расширение возможностей**: Теперь поддерживается **распознавание печатей**, **обнаружение текста** и расширение до **111 языков** (включая тибетское письмо Китая и бенгальский язык).
+ * **Работа с длинными документами**: Поддержка автоматического объединения таблиц на нескольких страницах и иерархической идентификации заголовков.
+ * **Попробуйте сейчас**: Доступно на [HuggingFace](https://huggingface.co/PaddlePaddle/PaddleOCR-VL-1.5) или на нашем [официальном сайте](https://www.paddleocr.com).
+
+
+
+
+2025.10.16: Выпуск PaddleOCR 3.3.0
+
+- Выпуск PaddleOCR-VL:
+ - **Описание модели**:
+ - **PaddleOCR-VL** — это SOTA-модель с эффективным использованием ресурсов, разработанная специально для разбора документов. Её ключевым компонентом является PaddleOCR-VL-0.9B — компактная, но мощная визуально-языковая модель (VLM), объединяющая динамический визуальный энкодер с переменным разрешением в стиле NaViT с языковой моделью ERNIE-4.5-0.3B для точного распознавания элементов. **Эта инновационная модель эффективно поддерживает 109 языков и превосходно справляется с распознаванием сложных элементов (например, текста, таблиц, формул и диаграмм), сохраняя минимальное потребление ресурсов**. По результатам комплексных оценок на широко используемых публичных тестах и внутренних тестах PaddleOCR-VL достигает SOTA-производительности как в разборе документов на уровне страниц, так и в распознавании элементов. Она значительно превосходит существующие решения, демонстрирует высокую конкурентоспособность по сравнению с ведущими VLM и обеспечивает высокую скорость вывода. Эти преимущества делают её высокопригодной для практического развёртывания в реальных сценариях. Модель опубликована на [HuggingFace](https://huggingface.co/PaddlePaddle/PaddleOCR-VL). Приглашаем всех скачать и использовать! Дополнительная информация доступна в разделе [PaddleOCR-VL](https://www.paddleocr.ai/latest/version3.x/algorithm/PaddleOCR-VL/PaddleOCR-VL.html).
+
+ - **Основные возможности**:
+ - **Компактная, но мощная архитектура VLM**: Представлена новая визуально-языковая модель, специально разработанная для ресурсоэффективного вывода, достигающая выдающейся производительности в распознавании элементов. Благодаря интеграции динамического высокоразрешающего визуального энкодера в стиле NaViT с лёгкой языковой моделью ERNIE-4.5-0.3B мы значительно повысили возможности распознавания и эффективность декодирования модели. Эта интеграция сохраняет высокую точность при снижении вычислительных требований, что делает её хорошо подходящей для эффективной и практической обработки документов.
+ - **SOTA-производительность в разборе документов**: PaddleOCR-VL достигает передовой производительности как в разборе документов на уровне страниц, так и в распознавании элементов. Она значительно превосходит существующие конвейерные решения и демонстрирует высокую конкурентоспособность по сравнению с ведущими визуально-языковыми моделями (VLM) в разборе документов. Кроме того, она превосходно справляется с распознаванием сложных элементов документов, таких как текст, таблицы, формулы и диаграммы, что делает её пригодной для широкого спектра сложных типов контента, включая рукописный текст и исторические документы. Это делает её высоко универсальной и подходящей для широкого спектра типов и сценариев документов.
+ - **Многоязычная поддержка**: PaddleOCR-VL поддерживает 109 языков, охватывая основные мировые языки, включая, но не ограничиваясь китайским, английским, японским, латинским и корейским, а также языки с различными системами письма и структурами, такие как русский (кириллица), арабский, хинди (письмо деванагари) и тайский. Широкий охват языков существенно повышает применимость нашей системы к многоязычным и глобализированным сценариям обработки документов.
+
+- Выпуск PP-OCRv5 — многоязычной модели распознавания:
+ - Улучшена точность и охват распознавания латинского письма; добавлена поддержка кириллицы, арабского, деванагари, телугу, тамильского и других языковых систем, охватывающих распознавание 109 языков. Модель имеет всего 2 МБ параметров, а точность некоторых моделей выросла более чем на 40% по сравнению с предыдущим поколением.
+
+
+
+
+
+2025.08.21: Выпуск PaddleOCR 3.2.0
+
+- **Значительные дополнения моделей:**
+ - Введены обучение, вывод и развёртывание моделей распознавания PP-OCRv5 для английского, тайского и греческого языков. **Модель PP-OCRv5 для английского языка обеспечивает улучшение на 11% в английских сценариях по сравнению с основной моделью PP-OCRv5, при этом модели распознавания тайского и греческого языков достигают точности 82,68% и 89,28% соответственно.**
+
+- **Улучшения возможностей развёртывания:**
+ - **Полная поддержка версий фреймворка PaddlePaddle 3.1.0 и 3.1.1.**
+ - **Комплексное обновление решения для локального развёртывания PP-OCRv5 на C++, теперь поддерживающего как Linux, так и Windows, с полным соответствием функций и идентичной точностью реализации на Python.**
+ - **Высокопроизводительный вывод теперь поддерживает CUDA 12, а вывод может выполняться с использованием бэкендов Paddle Inference или ONNX Runtime.**
+ - **Решение для высоконадёжного сервисного развёртывания теперь полностью открыто, позволяя пользователям при необходимости настраивать образы Docker и SDK.**
+ - Решение для высоконадёжного сервисного развёртывания также поддерживает вызов через вручную сформированные HTTP-запросы, что позволяет разрабатывать клиентский код на любом языке программирования.
+
+- **Поддержка бенчмарков:**
+ - **Все производственные конвейеры теперь поддерживают детализированное бенчмаркирование, позволяя измерять сквозное время вывода, а также задержки на уровне отдельных слоёв и модулей для анализа производительности. [Здесь](docs/version3.x/pipeline_usage/instructions/benchmark.en.md) описано, как настроить и использовать функцию бенчмарка.**
+ - **Документация обновлена и включает ключевые метрики для часто используемых конфигураций на основном оборудовании, такие как задержка вывода и использование памяти, предоставляя справочные данные для развёртывания.**
+
+- **Исправления ошибок:**
+ - Устранена проблема с неудачным сохранением журналов во время обучения модели.
+ - Обновлён компонент аугментации данных для моделей формул для совместимости с более новыми версиями зависимости albumentations, а также исправлены предупреждения о взаимоблокировке при использовании пакета tokenizers в многопроцессорных сценариях.
+ - Исправлены несоответствия в поведении переключателей (например, `use_chart_parsing`) в файлах конфигурации PP-StructureV3 по сравнению с другими конвейерами.
+
+- **Прочие улучшения:**
+ - **Разделены основные и дополнительные зависимости. Для базового распознавания текста требуются только минимальные основные зависимости; дополнительные зависимости для разбора документов и извлечения информации могут быть установлены по мере необходимости.**
+ - **Включена поддержка видеокарт NVIDIA RTX серии 50 на Windows; пользователи могут обратиться к [руководству по установке](docs/version3.x/installation.en.md) для получения информации о соответствующих версиях фреймворка PaddlePaddle.**
+ - **Модели серии PP-OCR теперь поддерживают возврат координат отдельных символов.**
+ - Добавлены источники загрузки моделей AIStudio, ModelScope и другие, позволяющие пользователям указывать источник для загрузки моделей.
+ - Добавлена поддержка преобразования диаграмм в таблицы через модуль PP-Chart2Table.
+ - Оптимизированы описания в документации для улучшения удобства использования.
+
+
+
+[История изменений](https://paddlepaddle.github.io/PaddleOCR/latest/en/update/update.html)
+
+
+## 🚀 Быстрый старт
+
+### Шаг 1: Попробуйте онлайн
+Официальный сайт PaddleOCR предоставляет интерактивный **Центр опыта** и **API** — без необходимости настройки, просто один клик для ознакомления.
+
+👉 [Посетить официальный сайт](https://www.paddleocr.com)
+
+### Шаг 2: Локальное развёртывание
+Для локального использования обратитесь к следующей документации в соответствии с вашими потребностями:
+
+- **Серия PP-OCR**: См. [Документацию PP-OCR](https://www.paddleocr.ai/latest/en/version3.x/pipeline_usage/OCR.html)
+- **Серия PaddleOCR-VL**: См. [Документацию PaddleOCR-VL](https://www.paddleocr.ai/latest/en/version3.x/pipeline_usage/PaddleOCR-VL.html)
+- **PP-StructureV3**: См. [Документацию PP-StructureV3](https://www.paddleocr.ai/latest/en/version3.x/pipeline_usage/PP-StructureV3.html)
+- **Дополнительные возможности**: См. [Документацию по дополнительным возможностям](https://www.paddleocr.ai/latest/en/version3.x/pipeline_usage/pipeline_overview.html)
+
+
+## 🧩 Дополнительные возможности
+
+- Конвертация моделей в формат ONNX: [Получение моделей ONNX](https://paddlepaddle.github.io/PaddleOCR/latest/en/version3.x/inference_deployment/others/obtaining_onnx_models.html).
+- Ускорение вывода с использованием движков OpenVINO, ONNX Runtime, TensorRT или выполнение вывода с использованием моделей в формате ONNX: [Высокопроизводительный вывод](https://paddlepaddle.github.io/PaddleOCR/latest/en/version3.x/inference_deployment/local_inference/high_performance_inference.html).
+- Ускорение вывода с использованием нескольких GPU и многопроцессорной обработки: [Параллельный вывод для конвейеров](https://paddlepaddle.github.io/PaddleOCR/latest/en/version3.x/pipeline_usage/instructions/parallel_inference.html).
+- Интеграция PaddleOCR в приложения, написанные на C++, C#, Java и др.: [Сервисное развёртывание](https://paddlepaddle.github.io/PaddleOCR/latest/en/version3.x/inference_deployment/serving/serving.html).
+
+## 🔄 Краткий обзор результатов выполнения
+
+### PP-OCRv5
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+| Официальный аккаунт PaddlePaddle в WeChat | Присоединиться к группе технических обсуждений |
+| :---: | :---: |
+|
|
|
+
+
+| Название проекта | Описание |
+| ------------ | ----------- |
+| [Dify](https://github.com/langgenius/dify)
|Готовая к производству платформа для разработки агентных рабочих процессов.|
+| [RAGFlow](https://github.com/infiniflow/ragflow)
|RAG-движок на основе глубокого понимания документов.|
+| [pathway](https://github.com/pathwaycom/pathway)
|Python ETL-фреймворк для потоковой обработки, аналитики в реальном времени, конвейеров LLM и RAG.|
+| [MinerU](https://github.com/opendatalab/MinerU)
|Инструмент для конвертации документов различных типов в Markdown.|
+| [Umi-OCR](https://github.com/hiroi-sora/Umi-OCR)
|Бесплатное программное обеспечение для пакетного офлайн-OCR с открытым исходным кодом.|
+| [cherry-studio](https://github.com/CherryHQ/cherry-studio)
|Настольный клиент с поддержкой нескольких провайдеров LLM.|
+| [haystack](https://github.com/deepset-ai/haystack)
|Фреймворк оркестрации AI для создания настраиваемых, готовых к производству приложений LLM.|
+| [OmniParser](https://github.com/microsoft/OmniParser)
|OmniParser: инструмент разбора экрана для агента GUI на основе чистого зрения.|
+| [QAnything](https://github.com/netease-youdao/QAnything)
|Вопросы и ответы на основе чего угодно.|
+| [Узнать о других проектах](./awesome_projects.md) | [Другие проекты на основе PaddleOCR](./awesome_projects.md)|
+
+
+
+
+
+
+
+
+
+
+
+
全球領先的 OCR 工具包與文檔 AI 引擎
+
+
+[English](../README.md) | [简体中文](./README_cn.md)| 繁體中文 | [日本語](./README_ja.md) | [한국어](./README_ko.md) | [Français](./README_fr.md) | [Русский](./README_ru.md) | [Español](./README_es.md) | [العربية](./README_ar.md)
+
+
+
+[](https://pepy.tech/projects/paddleocr)
+[](https://github.com/PaddlePaddle/PaddleOCR/network/dependents)
+
+
+
+
+[](https://www.paddleocr.com)
+[](https://deepwiki.com/PaddlePaddle/PaddleOCR)
+[](../LICENSE)
+
+
+
+
+
+
+2026.05.28: PaddleOCR 3.6.0 發布
+
+- PaddleOCR-VL-1.6 核心亮點:
+
+ - **全新 SOTA 精度**:OmniDocBench v1.6 突破 96.3%,OmniDocBench v1.5 和 Real5-OmniDocBench 同步刷新 SOTA。
+ - **能力全面升級**:表格、古籍、生僻字識別大幅提升。
+ - **無縫遷移**:模型結構與 PaddleOCR-VL-1.5 完全一致,零成本適配。
+ - **立即試用**:[HuggingFace](https://huggingface.co/PaddlePaddle/PaddleOCR-VL-1.6) 或[官方網站](https://www.paddleocr.com)。
+
+
+
+2026.04.21: PaddleOCR 3.5.0 發布
+
+* **推理後端靈活切換**:支持在飛槳靜態圖、飛槳動態圖和 Transformers 之間無縫切換。深度適配 Hugging Face 生態,20 個主要模型支持以 Transformers 作為推理後端。
+* **常見文檔格式轉 Markdown**:支持將 Word、Excel、PowerPoint 等常見文檔格式轉換為 Markdown。
+* **解析結果導出 DOCX**:`PaddleOCR-VL` 系列、`PP-StructureV3` 和 `PP-DocTranslation` 現已支持將解析結果導出為 DOCX,便於在 Microsoft Word 中查看和編輯。
+* **官方瀏覽器推理 SDK**:發布官方瀏覽器推理 SDK `PaddleOCR.js`,支持在瀏覽器中運行 `PP-OCRv5`。
+
+
+
+
+2026.01.29: PaddleOCR 3.4.0 發布
+* PaddleOCR-VL-1.5 (SOTA 0.9B VLM):我們最新的旗艦文檔解析模型現已上線!
+ * **OmniDocBench 94.5%準確率**:超越頂級通用大模型和專業文檔解析模型。
+ * **現實5大場景文檔解析的SOTA性能**:首次引入**PP-DocLayoutV3**算法進行不規則形狀定位,掌控5種艱難場景:傾斜、彎曲、掃描、光照和屏幕拍照。
+ * **能力拓展**:現已支持**印章識別**、**文本識別**,並擴展至**111種語言**(包括中國的藏文和孟加拉語)。
+ * **長文檔跨頁解析**:支持自動跨頁表格合併和分層標題識別。
+ * **立即試用**:可在[HuggingFace](https://huggingface.co/PaddlePaddle/PaddleOCR-VL-1.5)或我們的[官方網站](https://www.paddleocr.com)使用。
+
+
+
+
+2025.10.16: PaddleOCR 3.3.0 發布
+
+- **發布PaddleOCR-VL**:
+ - **模型介紹**:
+ - **PaddleOCR-VL** 是一款先進、高效的文檔解析模型,專為文檔中的元素識別設計。其核心組件為 PaddleOCR-VL-0.9B,這是一種緊湊而強大的視覺語言模型(VLM),它由 NaViT 風格的動態分辨率視覺編碼器與 ERNIE-4.5-0.3B 語言模型組成,能夠實現精準的元素識別。**該模型支持 109 種語言,並在識別複雜元素(如文本、表格、公式和圖表)方面表現出色,同時保持極低的資源消耗。通過在廣泛使用的公開基準與內部基準上的全面評測,PaddleOCR-VL 在頁級級文檔解析與元素級識別均達到 SOTA 表現**。它顯著優於現有的基於Pipeline方案和文檔解析多模態方案以及先進的通用多模態大模型,並具備更快的推理速度。這些優勢使其非常適合在真實場景中落地部署。模型已發布至[HuggingFace](https://huggingface.co/PaddlePaddle/PaddleOCR-VL),歡迎大家下載使用!更多介紹內容請點擊[PaddleOCR-VL](https://www.paddleocr.ai/latest/version3.x/algorithm/PaddleOCR-VL/PaddleOCR-VL.html)。
+
+ - **特性**:
+ - **緊湊而強大的視覺語言模型架構**:我們提出了一種新的視覺語言模型,專為資源高效的推理而設計,在元素識別方面表現出色。通過將NaViT風格的動態高分辨率視覺編碼器與輕量級的ERNIE-4.5-0.3B語言模型結合,我們顯著增強了模型的識別能力和解碼效率。這種集成在保持高準確率的同時降低了計算需求,使其非常適合高效且實用的文檔處理應用。
+ - **文檔解析的SOTA性能**:PaddleOCR-VL在頁面級文檔解析和元素級識別中達到了最先進的性能。它顯著優於現有的基於流水線的解決方案,並在文檔解析中展現出與領先的視覺語言模型(VLMs)競爭的強勁實力。此外,它在識別複雜的文檔元素(如文本、表格、公式和圖表)方面表現出色,使其適用於包括手寫文本和歷史文獻在內的各種具有挑戰性的內容類型。這使得它具有高度的多功能性,適用於廣泛的文檔類型和場景。
+ - **多語言支持**:PaddleOCR-VL支持109種語言,覆蓋了主要的全球語言,包括但不限於中文、英文、日文、拉丁文和韓文,以及使用不同文字和結構的語言,如俄語(西里爾字母)、阿拉伯語、印地語(天城文)和泰語。這種廣泛的語言覆蓋大大增強了我們系統在多語言和全球化文檔處理場景中的適用性。
+
+- **發布PP-OCRv5小語種識別模型**:
+ - 優化拉丁文識別的準度和廣度,新增西里爾文、阿拉伯文、天城文、泰盧固語、泰米爾語等語系,覆蓋109種語言文字的識別。模型參數量僅為2M,部分模型精度較上一代提升40%以上。
+
+
+
+
+
+2025.08.21: PaddleOCR 3.2.0 發布
+
+- **重要模型新增:**
+ - 新增 PP-OCRv5 英文、泰文、希臘文識別模型的訓練、推理、部署。**其中 PP-OCRv5 英文模型較 PP-OCRv5 主模型在英文場景提升 11%,泰文識別模型精度 82.68%,希臘文識別模型精度 89.28%。**
+
+- **部署能力升級:**
+ - **全面支持飛槳框架 3.1.0 和 3.1.1 版本。**
+ - **全面升級 PP-OCRv5 C++ 本地部署方案,支持 Linux、Windows,功能及精度效果與 Python 方案保持一致。**
+ - **高性能推理支持 CUDA 12,可使用 Paddle Inference、ONNX Runtime 後端推理。**
+ - **高穩定性服務化部署方案全面開源,支持用戶根據需求對 Docker 鏡像和 SDK 進行定制化修改。**
+ - 高穩定性服務化部署方案支持通過手動構造HTTP請求的方式調用,該方式允許客戶端代碼使用任意編程語言編寫。
+
+- **Benchmark支持**:
+ - **全部產線支持產線細粒度 benchmark,能夠測量產線端到端推理時間以及逐層、逐模塊的耗時數據,可用於輔助產線性能分析。可以參考[文檔](../docs/version3.x/pipeline_usage/instructions/benchmark.md)來進行性能測試。**
+ - **文檔中補充各產線常用配置在主流硬件上的關鍵指標,包括推理耗時和內存佔用等,為用戶部署提供參考。**
+
+- **Bug修復:**
+ - 修復模型訓練時訓練日誌保存失敗的問題。
+ - 對公式模型的數據增強部分進行了版本兼容性升級,以適應新版本的 albumentations 依賴,並修復了在多進程使用 tokenizers 依賴包時出現的死鎖警告。
+ - 修復 PP-StructureV3 配置文件中的 `use_chart_parsing` 等開關行為與其他產線不統一的問題。
+
+- **其他升級:**
+ - **分離必要依賴與可選依賴。使用基礎文字識別功能時,僅需安裝少量核心依賴;若需文檔解析、信息抽取等功能,用戶可按需選擇安裝額外依賴。**
+ - **支持 Windows 用戶使用英偉達 50 系顯卡,可根據 [安裝文檔](../docs/version3.x/installation.md) 安裝對應版本的 paddle 框架。**
+ - **PP-OCR 系列模型支持返回單文字坐標。**
+ - 模型新增 AIStudio、ModelScope 等下載源。可指定相關下載源下載對應的模型。
+ - 支持圖表轉表 PP-Chart2Table 單功能模塊推理能力。
+ - 優化部分使用文檔中的描述,提升易用性。
+
+
+
+[歷史日誌](https://paddlepaddle.github.io/PaddleOCR/latest/en/update/update.html)
+
+
+## 🚀 快速開始
+
+### 步驟 1: 在線體驗
+PaddleOCR官方網站提供交互式**體驗中心**和**APIs**——無需設置,一鍵體驗。
+
+👉 [訪問官方網站](https://www.paddleocr.com)
+
+### 步驟 2: 本地部署
+對於本地使用,請根據您的需求參考以下文檔:
+
+- **PP-OCR系列**:查看[PP-OCR文檔](https://www.paddleocr.ai/latest/version3.x/pipeline_usage/OCR.html)
+- **PaddleOCR-VL系列**:查看[PaddleOCR-VL文檔](https://www.paddleocr.ai/latest/version3.x/pipeline_usage/PaddleOCR-VL.html)
+- **PP-StructureV3**:查看[PP-StructureV3文檔](https://www.paddleocr.ai/latest/version3.x/pipeline_usage/PP-StructureV3.html)
+- **更多能力**:查看[更多能力文檔](https://www.paddleocr.ai/latest/version3.x/pipeline_usage/pipeline_overview.html)
+
+
+## 🧩 更多功能
+
+- 將模型轉換為ONNX格式: [獲取ONNX模型](https://paddlepaddle.github.io/PaddleOCR/latest/version3.x/inference_deployment/others/obtaining_onnx_models.html)。
+- 使用OpenVINO、ONNX Runtime、TensorRT等引擎加速推理,或使用ONNX格式模型進行推理: [高性能推理](https://paddlepaddle.github.io/PaddleOCR/latest/version3.x/inference_deployment/local_inference/high_performance_inference.html)。
+- 使用多GPU和多進程加速推理: [流水線並行推理](https://paddlepaddle.github.io/PaddleOCR/latest/version3.x/pipeline_usage/instructions/parallel_inference.html)。
+- 將PaddleOCR集成到C++、C#、Java等語言編寫的應用程序中: [服務化部署](https://paddlepaddle.github.io/PaddleOCR/latest/version3.x/inference_deployment/serving/serving.html)。
+
+## 🔄 執行結果快速預覽
+
+### PP-OCRv5
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+| PaddlePaddle 微信公眾號 | 加入技術討論群 |
+| :---: | :---: |
+|
|
|
+
+
+PaddleOCR 的發展離不開社區貢獻!💗衷心感謝所有開發者、合作夥伴與貢獻者!
+| 項目名稱 | 簡介 |
+| ------------ | ----------- |
+| [RAGFlow](https://github.com/infiniflow/ragflow)
|基於RAG的AI工作流引擎|
+| [pathway](https://github.com/pathwaycom/pathway)
|用於流處理、實時分析、LLM流水線和RAG的Python ETL框架|
+| [MinerU](https://github.com/opendatalab/MinerU)
|多類型文檔轉換Markdown工具|
+| [Umi-OCR](https://github.com/hiroi-sora/Umi-OCR)
|開源批量離線OCR軟件|
+| [cherry-studio](https://github.com/CherryHQ/cherry-studio)
|一個支持多個LLM提供商的桌面客戶端|
+| [OmniParser](https://github.com/microsoft/OmniParser)
|基於純視覺的GUI智能體屏幕解析工具|
+| [QAnything](https://github.com/netease-youdao/QAnything)
|基於任意內容的問答系統|
+| [PDF-Extract-Kit](https://github.com/opendatalab/PDF-Extract-Kit)
|高效複雜PDF文檔提取工具包|
+| [Dango-Translator](https://github.com/PantsuDango/Dango-Translator)
|屏幕實時翻譯工具|
+| [更多項目](../awesome_projects.md) | [更多基於PaddleOCR的項目](../awesome_projects.md) |
+
+
+
+
+
[[^/\s)\]\"'<>]+)"
+ rf"(?P/[^\s)\]\"'<>]*)?"
+ )
+
+
+def find_forbidden_links(root, repo_slug, forbidden_refs):
+ root = Path(root)
+ forbidden_refs = set(forbidden_refs)
+ link_pattern = _compile_link_pattern(repo_slug)
+ violations = []
+
+ for path in sorted(root.rglob("*.md")):
+ if not path.is_file():
+ continue
+ for line_number, line in enumerate(
+ path.read_text(encoding="utf-8").splitlines(), 1
+ ):
+ for match in link_pattern.finditer(line):
+ ref = match.group("ref")
+ if ref in forbidden_refs:
+ violations.append(
+ Violation(
+ path=path,
+ line_number=line_number,
+ ref=ref,
+ url=match.group(0),
+ )
+ )
+ return violations
+
+
+def main(argv=None):
+ parser = argparse.ArgumentParser(
+ description="Reject docs links that point to moving GitHub source refs."
+ )
+ parser.add_argument("--root", default="docs", help="Directory to scan.")
+ parser.add_argument(
+ "--repo-slug", required=True, help="Example: PaddlePaddle/PaddleOCR"
+ )
+ parser.add_argument(
+ "--forbidden-ref",
+ action="append",
+ required=True,
+ help="Moving source ref to reject. Can be passed multiple times.",
+ )
+ args = parser.parse_args(argv)
+
+ violations = find_forbidden_links(
+ args.root,
+ repo_slug=args.repo_slug,
+ forbidden_refs=set(args.forbidden_ref),
+ )
+ if violations:
+ for violation in violations:
+ print(
+ f"{violation.path}:{violation.line_number}: "
+ f"forbidden GitHub ref '{violation.ref}' in {violation.url}"
+ )
+ return 1
+ return 0
+
+
+if __name__ == "__main__":
+ raise SystemExit(main())
diff --git a/ocr-studio/PaddleOCR/tools/end2end/convert_ppocr_label.py b/ocr-studio/PaddleOCR/tools/end2end/convert_ppocr_label.py
new file mode 100644
index 0000000000000000000000000000000000000000..c64b9ed168113879182262b609bea692fcb73165
--- /dev/null
+++ b/ocr-studio/PaddleOCR/tools/end2end/convert_ppocr_label.py
@@ -0,0 +1,100 @@
+# Copyright (c) 2022 PaddlePaddle Authors. All Rights Reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+import numpy as np
+import json
+import os
+
+
+def poly_to_string(poly):
+ if len(poly.shape) > 1:
+ poly = np.array(poly).flatten()
+
+ string = "\t".join(str(i) for i in poly)
+ return string
+
+
+def convert_label(label_dir, mode="gt", save_dir="./save_results/"):
+ if not os.path.exists(label_dir):
+ raise ValueError(f"The file {label_dir} does not exist!")
+
+ assert label_dir != save_dir, "hahahhaha"
+
+ label_file = open(label_dir, 'r')
+ data = label_file.readlines()
+
+ gt_dict = {}
+
+ for line in data:
+ try:
+ tmp = line.split('\t')
+ assert len(tmp) == 2, ""
+ except:
+ tmp = line.strip().split(' ')
+
+ gt_lists = []
+
+ if tmp[0].split('/')[0] is not None:
+ img_path = tmp[0]
+ anno = json.loads(tmp[1])
+ gt_collect = []
+ for dic in anno:
+ #txt = dic['transcription'].replace(' ', '') # ignore blank
+ txt = dic['transcription']
+ if 'score' in dic and float(dic['score']) < 0.5:
+ continue
+ if u'\u3000' in txt: txt = txt.replace(u'\u3000', u' ')
+ #while ' ' in txt:
+ # txt = txt.replace(' ', '')
+ poly = np.array(dic['points']).flatten()
+ if txt == "###":
+ txt_tag = 1 ## ignore 1
+ else:
+ txt_tag = 0
+ if mode == "gt":
+ gt_label = poly_to_string(poly) + "\t" + str(
+ txt_tag) + "\t" + txt + "\n"
+ else:
+ gt_label = poly_to_string(poly) + "\t" + txt + "\n"
+
+ gt_lists.append(gt_label)
+
+ gt_dict[img_path] = gt_lists
+ else:
+ continue
+
+ if not os.path.exists(save_dir):
+ os.makedirs(save_dir)
+
+ for img_name in gt_dict.keys():
+ save_name = img_name.split("/")[-1]
+ save_file = os.path.join(save_dir, save_name + ".txt")
+ with open(save_file, "w") as f:
+ f.writelines(gt_dict[img_name])
+
+ print("The convert label saved in {}".format(save_dir))
+
+
+def parse_args():
+ import argparse
+ parser = argparse.ArgumentParser(description="args")
+ parser.add_argument("--label_path", type=str, required=True)
+ parser.add_argument("--save_folder", type=str, required=True)
+ parser.add_argument("--mode", type=str, default=False)
+ args = parser.parse_args()
+ return args
+
+
+if __name__ == "__main__":
+ args = parse_args()
+ convert_label(args.label_path, args.mode, args.save_folder)
diff --git a/ocr-studio/PaddleOCR/tools/end2end/draw_html.py b/ocr-studio/PaddleOCR/tools/end2end/draw_html.py
new file mode 100644
index 0000000000000000000000000000000000000000..fcac8ad3bfb6f0d1fcc48ea026b0febe60a001c0
--- /dev/null
+++ b/ocr-studio/PaddleOCR/tools/end2end/draw_html.py
@@ -0,0 +1,73 @@
+# Copyright (c) 2022 PaddlePaddle Authors. All Rights Reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import os
+import argparse
+
+
+def str2bool(v):
+ return v.lower() in ("true", "t", "1")
+
+
+def init_args():
+ parser = argparse.ArgumentParser()
+ parser.add_argument("--image_dir", type=str, default="")
+ parser.add_argument("--save_html_path", type=str, default="./default.html")
+ parser.add_argument("--width", type=int, default=640)
+ return parser
+
+
+def parse_args():
+ parser = init_args()
+ return parser.parse_args()
+
+
+def draw_debug_img(args):
+
+ html_path = args.save_html_path
+
+ err_cnt = 0
+ with open(html_path, 'w') as html:
+ html.write('\n\n')
+ html.write(']\n')
+ html.write(
+ ""
+ )
+ image_list = []
+ path = args.image_dir
+ for i, filename in enumerate(sorted(os.listdir(path))):
+ if filename.endswith("txt"): continue
+ # The image path
+ base = "{}/{}".format(path, filename)
+ html.write("\n")
+ html.write(f'| {filename}\n GT')
+ html.write(f' | GT\n | ')
+
+ html.write("
\n")
+ html.write('\n')
+ html.write('
\n')
+ html.write('\n\n')
+ print(f"The html file saved in {html_path}")
+ return
+
+
+if __name__ == "__main__":
+
+ args = parse_args()
+
+ draw_debug_img(args)
diff --git a/ocr-studio/PaddleOCR/tools/end2end/eval_end2end.py b/ocr-studio/PaddleOCR/tools/end2end/eval_end2end.py
new file mode 100644
index 0000000000000000000000000000000000000000..dd37940845b60d55291b40b8cd50d6afd5b91f94
--- /dev/null
+++ b/ocr-studio/PaddleOCR/tools/end2end/eval_end2end.py
@@ -0,0 +1,193 @@
+# Copyright (c) 2022 PaddlePaddle Authors. All Rights Reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import os
+import re
+import sys
+import shapely
+from shapely.geometry import Polygon
+import numpy as np
+from collections import defaultdict
+import operator
+import editdistance
+
+
+def strQ2B(ustring):
+ rstring = ""
+ for uchar in ustring:
+ inside_code = ord(uchar)
+ if inside_code == 12288:
+ inside_code = 32
+ elif (inside_code >= 65281 and inside_code <= 65374):
+ inside_code -= 65248
+ rstring += chr(inside_code)
+ return rstring
+
+
+def polygon_from_str(polygon_points):
+ """
+ Create a shapely polygon object from gt or dt line.
+ """
+ polygon_points = np.array(polygon_points).reshape(4, 2)
+ polygon = Polygon(polygon_points).convex_hull
+ return polygon
+
+
+def polygon_iou(poly1, poly2):
+ """
+ Intersection over union between two shapely polygons.
+ """
+ if not poly1.intersects(
+ poly2): # this test is fast and can accelerate calculation
+ iou = 0
+ else:
+ try:
+ inter_area = poly1.intersection(poly2).area
+ union_area = poly1.area + poly2.area - inter_area
+ iou = float(inter_area) / union_area
+ except shapely.geos.TopologicalError:
+ # except Exception as e:
+ # print(e)
+ print('shapely.geos.TopologicalError occurred, iou set to 0')
+ iou = 0
+ return iou
+
+
+def ed(str1, str2):
+ return editdistance.eval(str1, str2)
+
+
+def e2e_eval(gt_dir, res_dir, ignore_blank=False):
+ print('start testing...')
+ iou_thresh = 0.5
+ val_names = os.listdir(gt_dir)
+ num_gt_chars = 0
+ gt_count = 0
+ dt_count = 0
+ hit = 0
+ ed_sum = 0
+
+ for i, val_name in enumerate(val_names):
+ with open(os.path.join(gt_dir, val_name), encoding='utf-8') as f:
+ gt_lines = [o.strip() for o in f.readlines()]
+ gts = []
+ ignore_masks = []
+ for line in gt_lines:
+ parts = line.strip().split('\t')
+ # ignore illegal data
+ if len(parts) < 9:
+ continue
+ assert (len(parts) < 11)
+ if len(parts) == 9:
+ gts.append(parts[:8] + [''])
+ else:
+ gts.append(parts[:8] + [parts[-1]])
+
+ ignore_masks.append(parts[8])
+
+ val_path = os.path.join(res_dir, val_name)
+ if not os.path.exists(val_path):
+ dt_lines = []
+ else:
+ with open(val_path, encoding='utf-8') as f:
+ dt_lines = [o.strip() for o in f.readlines()]
+ dts = []
+ for line in dt_lines:
+ # print(line)
+ parts = line.strip().split("\t")
+ assert (len(parts) < 10), "line error: {}".format(line)
+ if len(parts) == 8:
+ dts.append(parts + [''])
+ else:
+ dts.append(parts)
+
+ dt_match = [False] * len(dts)
+ gt_match = [False] * len(gts)
+ all_ious = defaultdict(tuple)
+ for index_gt, gt in enumerate(gts):
+ gt_coors = [float(gt_coor) for gt_coor in gt[0:8]]
+ gt_poly = polygon_from_str(gt_coors)
+ for index_dt, dt in enumerate(dts):
+ dt_coors = [float(dt_coor) for dt_coor in dt[0:8]]
+ dt_poly = polygon_from_str(dt_coors)
+ iou = polygon_iou(dt_poly, gt_poly)
+ if iou >= iou_thresh:
+ all_ious[(index_gt, index_dt)] = iou
+ sorted_ious = sorted(
+ all_ious.items(), key=operator.itemgetter(1), reverse=True)
+ sorted_gt_dt_pairs = [item[0] for item in sorted_ious]
+
+ # matched gt and dt
+ for gt_dt_pair in sorted_gt_dt_pairs:
+ index_gt, index_dt = gt_dt_pair
+ if gt_match[index_gt] == False and dt_match[index_dt] == False:
+ gt_match[index_gt] = True
+ dt_match[index_dt] = True
+ if ignore_blank:
+ gt_str = strQ2B(gts[index_gt][8]).replace(" ", "")
+ dt_str = strQ2B(dts[index_dt][8]).replace(" ", "")
+ else:
+ gt_str = strQ2B(gts[index_gt][8])
+ dt_str = strQ2B(dts[index_dt][8])
+ if ignore_masks[index_gt] == '0':
+ ed_sum += ed(gt_str, dt_str)
+ num_gt_chars += len(gt_str)
+ if gt_str == dt_str:
+ hit += 1
+ gt_count += 1
+ dt_count += 1
+
+ # unmatched dt
+ for tindex, dt_match_flag in enumerate(dt_match):
+ if dt_match_flag == False:
+ dt_str = dts[tindex][8]
+ gt_str = ''
+ ed_sum += ed(dt_str, gt_str)
+ dt_count += 1
+
+ # unmatched gt
+ for tindex, gt_match_flag in enumerate(gt_match):
+ if gt_match_flag == False and ignore_masks[tindex] == '0':
+ dt_str = ''
+ gt_str = gts[tindex][8]
+ ed_sum += ed(gt_str, dt_str)
+ num_gt_chars += len(gt_str)
+ gt_count += 1
+
+ eps = 1e-9
+ print('hit, dt_count, gt_count', hit, dt_count, gt_count)
+ precision = hit / (dt_count + eps)
+ recall = hit / (gt_count + eps)
+ fmeasure = 2.0 * precision * recall / (precision + recall + eps)
+ avg_edit_dist_img = ed_sum / len(val_names)
+ avg_edit_dist_field = ed_sum / (gt_count + eps)
+ character_acc = 1 - ed_sum / (num_gt_chars + eps)
+
+ print('character_acc: %.2f' % (character_acc * 100) + "%")
+ print('avg_edit_dist_field: %.2f' % (avg_edit_dist_field))
+ print('avg_edit_dist_img: %.2f' % (avg_edit_dist_img))
+ print('precision: %.2f' % (precision * 100) + "%")
+ print('recall: %.2f' % (recall * 100) + "%")
+ print('fmeasure: %.2f' % (fmeasure * 100) + "%")
+
+
+if __name__ == '__main__':
+ # if len(sys.argv) != 3:
+ # print("python3 ocr_e2e_eval.py gt_dir res_dir")
+ # exit(-1)
+ # gt_folder = sys.argv[1]
+ # pred_folder = sys.argv[2]
+ gt_folder = sys.argv[1]
+ pred_folder = sys.argv[2]
+ e2e_eval(gt_folder, pred_folder)
diff --git a/ocr-studio/PaddleOCR/tools/end2end/readme.md b/ocr-studio/PaddleOCR/tools/end2end/readme.md
new file mode 100644
index 0000000000000000000000000000000000000000..636ee764aef35a551f729cce20c16357ddf4f495
--- /dev/null
+++ b/ocr-studio/PaddleOCR/tools/end2end/readme.md
@@ -0,0 +1,63 @@
+
+# 简介
+
+`tools/end2end`目录下存放了文本检测+文本识别pipeline串联预测的指标评测代码以及可视化工具。本节介绍文本检测+文本识别的端对端指标评估方式。
+
+
+## 端对端评测步骤
+
+**步骤一:**
+
+运行`tools/infer/predict_system.py`,得到保存的结果:
+
+```
+python3 tools/infer/predict_system.py --det_model_dir=./ch_PP-OCRv2_det_infer/ --rec_model_dir=./ch_PP-OCRv2_rec_infer/ --image_dir=./datasets/img_dir/ --draw_img_save_dir=./ch_PP-OCRv2_results/ --is_visualize=True
+```
+
+文本检测识别可视化图默认保存在`./ch_PP-OCRv2_results/`目录下,预测结果默认保存在`./ch_PP-OCRv2_results/system_results.txt`中,格式如下:
+```
+all-sum-510/00224225.jpg [{"transcription": "超赞", "points": [[8.0, 48.0], [157.0, 44.0], [159.0, 115.0], [10.0, 119.0]], "score": "0.99396634"}, {"transcription": "中", "points": [[202.0, 152.0], [230.0, 152.0], [230.0, 163.0], [202.0, 163.0]], "score": "0.09310734"}, {"transcription": "58.0m", "points": [[196.0, 192.0], [444.0, 192.0], [444.0, 240.0], [196.0, 240.0]], "score": "0.44041982"}, {"transcription": "汽配", "points": [[55.0, 263.0], [95.0, 263.0], [95.0, 281.0], [55.0, 281.0]], "score": "0.9986651"}, {"transcription": "成总店", "points": [[120.0, 262.0], [176.0, 262.0], [176.0, 283.0], [120.0, 283.0]], "score": "0.9929402"}, {"transcription": "K", "points": [[237.0, 286.0], [311.0, 286.0], [311.0, 345.0], [237.0, 345.0]], "score": "0.6074794"}, {"transcription": "88:-8", "points": [[203.0, 405.0], [477.0, 414.0], [475.0, 459.0], [201.0, 450.0]], "score": "0.7106863"}]
+```
+
+
+**步骤二:**
+
+将步骤一保存的数据转换为端对端评测需要的数据格式:
+
+修改 `tools/end2end/convert_ppocr_label.py`中的代码,convert_label函数中设置输入标签路径,Mode,保存标签路径等,对预测数据的GTlabel和预测结果的label格式进行转换。
+
+```
+python3 tools/end2end/convert_ppocr_label.py --mode=gt --label_path=path/to/label_txt --save_folder=save_gt_label
+
+python3 tools/end2end/convert_ppocr_label.py --mode=pred --label_path=path/to/pred_txt --save_folder=save_PPOCRV2_infer
+```
+
+得到如下结果:
+```
+├── ./save_gt_label/
+├── ./save_PPOCRV2_infer/
+```
+
+**步骤三:**
+
+执行端对端评测,运行`tools/eval_end2end.py`计算端对端指标,运行方式如下:
+
+```
+python3 tools/eval_end2end.py "gt_label_dir" "predict_label_dir"
+```
+
+比如:
+
+```
+python3 tools/eval_end2end.py ./save_gt_label/ ./save_PPOCRV2_infer/
+```
+将得到如下结果,fmeasure为主要关注的指标:
+```
+hit, dt_count, gt_count 1557 2693 3283
+character_acc: 61.77%
+avg_edit_dist_field: 3.08
+avg_edit_dist_img: 51.82
+precision: 57.82%
+recall: 47.43%
+fmeasure: 52.11%
+```
diff --git a/ocr-studio/PaddleOCR/tools/eval.py b/ocr-studio/PaddleOCR/tools/eval.py
new file mode 100644
index 0000000000000000000000000000000000000000..b4c69b6d37532103f1316eb3b7a14b472d741ed3
--- /dev/null
+++ b/ocr-studio/PaddleOCR/tools/eval.py
@@ -0,0 +1,146 @@
+# Copyright (c) 2020 PaddlePaddle Authors. All Rights Reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+from __future__ import absolute_import
+from __future__ import division
+from __future__ import print_function
+
+import os
+import sys
+
+__dir__ = os.path.dirname(os.path.abspath(__file__))
+sys.path.insert(0, __dir__)
+sys.path.insert(0, os.path.abspath(os.path.join(__dir__, '..')))
+
+import paddle
+from ppocr.data import build_dataloader, set_signal_handlers
+from ppocr.modeling.architectures import build_model
+from ppocr.postprocess import build_post_process
+from ppocr.metrics import build_metric
+from ppocr.utils.save_load import load_model
+import tools.program as program
+
+
+def main():
+ global_config = config['Global']
+ # build dataloader
+ set_signal_handlers()
+ valid_dataloader = build_dataloader(config, 'Eval', device, logger)
+
+ # build post process
+ post_process_class = build_post_process(config['PostProcess'],
+ global_config)
+
+ # build model
+ # for rec algorithm
+ if hasattr(post_process_class, 'character'):
+ char_num = len(getattr(post_process_class, 'character'))
+ if config['Architecture']["algorithm"] in ["Distillation",
+ ]: # distillation model
+ for key in config['Architecture']["Models"]:
+ if config['Architecture']['Models'][key]['Head'][
+ 'name'] == 'MultiHead': # for multi head
+ out_channels_list = {}
+ if config['PostProcess'][
+ 'name'] == 'DistillationSARLabelDecode':
+ char_num = char_num - 2
+ if config['PostProcess'][
+ 'name'] == 'DistillationNRTRLabelDecode':
+ char_num = char_num - 3
+ out_channels_list['CTCLabelDecode'] = char_num
+ out_channels_list['SARLabelDecode'] = char_num + 2
+ out_channels_list['NRTRLabelDecode'] = char_num + 3
+ config['Architecture']['Models'][key]['Head'][
+ 'out_channels_list'] = out_channels_list
+ else:
+ config['Architecture']["Models"][key]["Head"][
+ 'out_channels'] = char_num
+ elif config['Architecture']['Head'][
+ 'name'] == 'MultiHead': # for multi head
+ out_channels_list = {}
+ if config['PostProcess']['name'] == 'SARLabelDecode':
+ char_num = char_num - 2
+ if config['PostProcess']['name'] == 'NRTRLabelDecode':
+ char_num = char_num - 3
+ out_channels_list['CTCLabelDecode'] = char_num
+ out_channels_list['SARLabelDecode'] = char_num + 2
+ out_channels_list['NRTRLabelDecode'] = char_num + 3
+ config['Architecture']['Head'][
+ 'out_channels_list'] = out_channels_list
+ else: # base rec model
+ config['Architecture']["Head"]['out_channels'] = char_num
+
+ model = build_model(config['Architecture'])
+ extra_input_models = [
+ "SRN", "NRTR", "SAR", "SEED", "SVTR", "SVTR_LCNet", "VisionLAN",
+ "RobustScanner", "SVTR_HGNet"
+ ]
+ extra_input = False
+ if config['Architecture']['algorithm'] == 'Distillation':
+ for key in config['Architecture']["Models"]:
+ extra_input = extra_input or config['Architecture']['Models'][key][
+ 'algorithm'] in extra_input_models
+ else:
+ extra_input = config['Architecture']['algorithm'] in extra_input_models
+ if "model_type" in config['Architecture'].keys():
+ if config['Architecture']['algorithm'] == 'CAN':
+ model_type = 'can'
+ else:
+ model_type = config['Architecture']['model_type']
+ else:
+ model_type = None
+
+ # build metric
+ eval_class = build_metric(config['Metric'])
+ # amp
+ use_amp = config["Global"].get("use_amp", False)
+ amp_level = config["Global"].get("amp_level", 'O2')
+ amp_custom_black_list = config['Global'].get('amp_custom_black_list', [])
+ if use_amp:
+ AMP_RELATED_FLAGS_SETTING = {
+ 'FLAGS_cudnn_batchnorm_spatial_persistent': 1,
+ 'FLAGS_max_inplace_grad_add': 8,
+ }
+ paddle.set_flags(AMP_RELATED_FLAGS_SETTING)
+ scale_loss = config["Global"].get("scale_loss", 1.0)
+ use_dynamic_loss_scaling = config["Global"].get(
+ "use_dynamic_loss_scaling", False)
+ scaler = paddle.amp.GradScaler(
+ init_loss_scaling=scale_loss,
+ use_dynamic_loss_scaling=use_dynamic_loss_scaling)
+ if amp_level == "O2":
+ model = paddle.amp.decorate(
+ models=model, level=amp_level, master_weight=True)
+ else:
+ scaler = None
+
+ best_model_dict = load_model(
+ config, model, model_type=config['Architecture']["model_type"])
+ if len(best_model_dict):
+ logger.info('metric in ckpt ***************')
+ for k, v in best_model_dict.items():
+ logger.info('{}:{}'.format(k, v))
+
+ # start eval
+ metric = program.eval(model, valid_dataloader, post_process_class,
+ eval_class, model_type, extra_input, scaler,
+ amp_level, amp_custom_black_list)
+ logger.info('metric eval ***************')
+ for k, v in metric.items():
+ logger.info('{}:{}'.format(k, v))
+
+
+if __name__ == '__main__':
+ config, device, logger, vdl_writer = program.preprocess()
+ main()
diff --git a/ocr-studio/PaddleOCR/tools/export_center.py b/ocr-studio/PaddleOCR/tools/export_center.py
new file mode 100644
index 0000000000000000000000000000000000000000..3f7a883528525bebe037de7f78847fd77a059142
--- /dev/null
+++ b/ocr-studio/PaddleOCR/tools/export_center.py
@@ -0,0 +1,78 @@
+# Copyright (c) 2020 PaddlePaddle Authors. All Rights Reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+from __future__ import absolute_import
+from __future__ import division
+from __future__ import print_function
+
+import os
+import sys
+import pickle
+
+__dir__ = os.path.dirname(os.path.abspath(__file__))
+sys.path.append(__dir__)
+sys.path.append(os.path.abspath(os.path.join(__dir__, '..')))
+
+from ppocr.data import build_dataloader, set_signal_handlers
+from ppocr.modeling.architectures import build_model
+from ppocr.postprocess import build_post_process
+from ppocr.utils.save_load import load_model
+from ppocr.utils.utility import print_dict
+import tools.program as program
+
+
+def main():
+ global_config = config['Global']
+ # build dataloader
+ config['Eval']['dataset']['name'] = config['Train']['dataset']['name']
+ config['Eval']['dataset']['data_dir'] = config['Train']['dataset'][
+ 'data_dir']
+ config['Eval']['dataset']['label_file_list'] = config['Train']['dataset'][
+ 'label_file_list']
+ set_signal_handlers()
+ eval_dataloader = build_dataloader(config, 'Eval', device, logger)
+
+ # build post process
+ post_process_class = build_post_process(config['PostProcess'],
+ global_config)
+
+ # build model
+ # for rec algorithm
+ if hasattr(post_process_class, 'character'):
+ char_num = len(getattr(post_process_class, 'character'))
+ config['Architecture']["Head"]['out_channels'] = char_num
+
+ #set return_features = True
+ config['Architecture']["Head"]["return_feats"] = True
+
+ model = build_model(config['Architecture'])
+
+ best_model_dict = load_model(config, model)
+ if len(best_model_dict):
+ logger.info('metric in ckpt ***************')
+ for k, v in best_model_dict.items():
+ logger.info('{}:{}'.format(k, v))
+
+ # get features from train data
+ char_center = program.get_center(model, eval_dataloader, post_process_class)
+
+ #serialize to disk
+ with open("train_center.pkl", 'wb') as f:
+ pickle.dump(char_center, f)
+ return
+
+
+if __name__ == '__main__':
+ config, device, logger, vdl_writer = program.preprocess()
+ main()
diff --git a/ocr-studio/PaddleOCR/tools/export_model.py b/ocr-studio/PaddleOCR/tools/export_model.py
new file mode 100644
index 0000000000000000000000000000000000000000..8228175ead1f76440249c92e6397ae1d9928e65f
--- /dev/null
+++ b/ocr-studio/PaddleOCR/tools/export_model.py
@@ -0,0 +1,293 @@
+# Copyright (c) 2020 PaddlePaddle Authors. All Rights Reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import os
+import sys
+
+__dir__ = os.path.dirname(os.path.abspath(__file__))
+sys.path.append(__dir__)
+sys.path.insert(0, os.path.abspath(os.path.join(__dir__, "..")))
+
+import argparse
+
+import paddle
+from paddle.jit import to_static
+
+from ppocr.modeling.architectures import build_model
+from ppocr.postprocess import build_post_process
+from ppocr.utils.save_load import load_model
+from ppocr.utils.logging import get_logger
+from tools.program import load_config, merge_config, ArgsParser
+
+
+def export_single_model(model,
+ arch_config,
+ save_path,
+ logger,
+ input_shape=None,
+ quanter=None):
+ if arch_config["algorithm"] == "SRN":
+ max_text_length = arch_config["Head"]["max_text_length"]
+ other_shape = [
+ paddle.static.InputSpec(
+ shape=[None, 1, 64, 256], dtype="float32"), [
+ paddle.static.InputSpec(
+ shape=[None, 256, 1],
+ dtype="int64"), paddle.static.InputSpec(
+ shape=[None, max_text_length, 1], dtype="int64"),
+ paddle.static.InputSpec(
+ shape=[None, 8, max_text_length, max_text_length],
+ dtype="int64"), paddle.static.InputSpec(
+ shape=[None, 8, max_text_length, max_text_length],
+ dtype="int64")
+ ]
+ ]
+ model = to_static(model, input_spec=other_shape)
+ elif arch_config["algorithm"] == "SAR":
+ other_shape = [
+ paddle.static.InputSpec(
+ shape=[None, 3, 48, 160], dtype="float32"),
+ [paddle.static.InputSpec(
+ shape=[None], dtype="float32")]
+ ]
+ model = to_static(model, input_spec=other_shape)
+ elif arch_config["algorithm"] in ["SVTR_LCNet", "SVTR_HGNet"]:
+ other_shape = [
+ paddle.static.InputSpec(
+ shape=[None, 3, 48, -1], dtype="float32"),
+ ]
+ model = to_static(model, input_spec=other_shape)
+ elif arch_config["algorithm"] in ["SVTR", "CPPD"]:
+ other_shape = [
+ paddle.static.InputSpec(
+ shape=[None] + input_shape, dtype="float32"),
+ ]
+ model = to_static(model, input_spec=other_shape)
+ elif arch_config["algorithm"] == "PREN":
+ other_shape = [
+ paddle.static.InputSpec(
+ shape=[None, 3, 64, 256], dtype="float32"),
+ ]
+ model = to_static(model, input_spec=other_shape)
+ elif arch_config["model_type"] == "sr":
+ other_shape = [
+ paddle.static.InputSpec(
+ shape=[None, 3, 16, 64], dtype="float32")
+ ]
+ model = to_static(model, input_spec=other_shape)
+ elif arch_config["algorithm"] == "ViTSTR":
+ other_shape = [
+ paddle.static.InputSpec(
+ shape=[None, 1, 224, 224], dtype="float32"),
+ ]
+ model = to_static(model, input_spec=other_shape)
+ elif arch_config["algorithm"] == "ABINet":
+ if not input_shape:
+ input_shape = [3, 32, 128]
+ other_shape = [
+ paddle.static.InputSpec(
+ shape=[None] + input_shape, dtype="float32"),
+ ]
+ model = to_static(model, input_spec=other_shape)
+ elif arch_config["algorithm"] in ["NRTR", "SPIN", 'RFL']:
+ other_shape = [
+ paddle.static.InputSpec(
+ shape=[None, 1, 32, 100], dtype="float32"),
+ ]
+ model = to_static(model, input_spec=other_shape)
+ elif arch_config["algorithm"] in ['SATRN']:
+ other_shape = [
+ paddle.static.InputSpec(
+ shape=[None, 3, 32, 100], dtype="float32"),
+ ]
+ model = to_static(model, input_spec=other_shape)
+ elif arch_config["algorithm"] == "VisionLAN":
+ other_shape = [
+ paddle.static.InputSpec(
+ shape=[None, 3, 64, 256], dtype="float32"),
+ ]
+ model = to_static(model, input_spec=other_shape)
+ elif arch_config["algorithm"] == "RobustScanner":
+ max_text_length = arch_config["Head"]["max_text_length"]
+ other_shape = [
+ paddle.static.InputSpec(
+ shape=[None, 3, 48, 160], dtype="float32"), [
+ paddle.static.InputSpec(
+ shape=[None, ], dtype="float32"),
+ paddle.static.InputSpec(
+ shape=[None, max_text_length], dtype="int64")
+ ]
+ ]
+ model = to_static(model, input_spec=other_shape)
+ elif arch_config["algorithm"] == "CAN":
+ other_shape = [[
+ paddle.static.InputSpec(
+ shape=[None, 1, None, None],
+ dtype="float32"), paddle.static.InputSpec(
+ shape=[None, 1, None, None], dtype="float32"),
+ paddle.static.InputSpec(
+ shape=[None, arch_config['Head']['max_text_length']],
+ dtype="int64")
+ ]]
+ model = to_static(model, input_spec=other_shape)
+ elif arch_config["algorithm"] in ["LayoutLM", "LayoutLMv2", "LayoutXLM"]:
+ input_spec = [
+ paddle.static.InputSpec(
+ shape=[None, 512], dtype="int64"), # input_ids
+ paddle.static.InputSpec(
+ shape=[None, 512, 4], dtype="int64"), # bbox
+ paddle.static.InputSpec(
+ shape=[None, 512], dtype="int64"), # attention_mask
+ paddle.static.InputSpec(
+ shape=[None, 512], dtype="int64"), # token_type_ids
+ paddle.static.InputSpec(
+ shape=[None, 3, 224, 224], dtype="int64"), # image
+ ]
+ if 'Re' in arch_config['Backbone']['name']:
+ input_spec.extend([
+ paddle.static.InputSpec(
+ shape=[None, 512, 3], dtype="int64"), # entities
+ paddle.static.InputSpec(
+ shape=[None, None, 2], dtype="int64"), # relations
+ ])
+ if model.backbone.use_visual_backbone is False:
+ input_spec.pop(4)
+ model = to_static(model, input_spec=[input_spec])
+ else:
+ infer_shape = [3, -1, -1]
+ if arch_config["model_type"] == "rec":
+ infer_shape = [3, 32, -1] # for rec model, H must be 32
+ if "Transform" in arch_config and arch_config[
+ "Transform"] is not None and arch_config["Transform"][
+ "name"] == "TPS":
+ logger.info(
+ "When there is tps in the network, variable length input is not supported, and the input size needs to be the same as during training"
+ )
+ infer_shape[-1] = 100
+ elif arch_config["model_type"] == "table":
+ infer_shape = [3, 488, 488]
+ if arch_config["algorithm"] == "TableMaster":
+ infer_shape = [3, 480, 480]
+ if arch_config["algorithm"] == "SLANet":
+ infer_shape = [3, -1, -1]
+ model = to_static(
+ model,
+ input_spec=[
+ paddle.static.InputSpec(
+ shape=[None] + infer_shape, dtype="float32")
+ ])
+
+ if arch_config["model_type"] != "sr" and arch_config["Backbone"][
+ "name"] == "PPLCNetV3":
+ # for rep lcnetv3
+ for layer in model.sublayers():
+ if hasattr(layer, "rep") and not getattr(layer, "is_repped"):
+ layer.rep()
+
+ if quanter is None:
+ paddle.jit.save(model, save_path)
+ else:
+ quanter.save_quantized_model(model, save_path)
+ logger.info("inference model is saved to {}".format(save_path))
+ return
+
+
+def main():
+ FLAGS = ArgsParser().parse_args()
+ config = load_config(FLAGS.config)
+ config = merge_config(config, FLAGS.opt)
+ logger = get_logger()
+ # build post process
+
+ post_process_class = build_post_process(config["PostProcess"],
+ config["Global"])
+
+ # build model
+ # for rec algorithm
+ if hasattr(post_process_class, "character"):
+ char_num = len(getattr(post_process_class, "character"))
+ if config["Architecture"]["algorithm"] in ["Distillation",
+ ]: # distillation model
+ for key in config["Architecture"]["Models"]:
+ if config["Architecture"]["Models"][key]["Head"][
+ "name"] == 'MultiHead': # multi head
+ out_channels_list = {}
+ if config['PostProcess'][
+ 'name'] == 'DistillationSARLabelDecode':
+ char_num = char_num - 2
+ if config['PostProcess'][
+ 'name'] == 'DistillationNRTRLabelDecode':
+ char_num = char_num - 3
+ out_channels_list['CTCLabelDecode'] = char_num
+ out_channels_list['SARLabelDecode'] = char_num + 2
+ out_channels_list['NRTRLabelDecode'] = char_num + 3
+ config['Architecture']['Models'][key]['Head'][
+ 'out_channels_list'] = out_channels_list
+ else:
+ config["Architecture"]["Models"][key]["Head"][
+ "out_channels"] = char_num
+ # just one final tensor needs to exported for inference
+ config["Architecture"]["Models"][key][
+ "return_all_feats"] = False
+ elif config['Architecture']['Head'][
+ 'name'] == 'MultiHead': # multi head
+ out_channels_list = {}
+ char_num = len(getattr(post_process_class, 'character'))
+ if config['PostProcess']['name'] == 'SARLabelDecode':
+ char_num = char_num - 2
+ if config['PostProcess']['name'] == 'NRTRLabelDecode':
+ char_num = char_num - 3
+ out_channels_list['CTCLabelDecode'] = char_num
+ out_channels_list['SARLabelDecode'] = char_num + 2
+ out_channels_list['NRTRLabelDecode'] = char_num + 3
+ config['Architecture']['Head'][
+ 'out_channels_list'] = out_channels_list
+ else: # base rec model
+ config["Architecture"]["Head"]["out_channels"] = char_num
+
+ # for sr algorithm
+ if config["Architecture"]["model_type"] == "sr":
+ config['Architecture']["Transform"]['infer_mode'] = True
+ model = build_model(config["Architecture"])
+ load_model(config, model, model_type=config['Architecture']["model_type"])
+ model.eval()
+
+ save_path = config["Global"]["save_inference_dir"]
+
+ arch_config = config["Architecture"]
+
+ if arch_config["algorithm"] in ["SVTR", "CPPD"] and arch_config["Head"][
+ "name"] != 'MultiHead':
+ input_shape = config["Eval"]["dataset"]["transforms"][-2][
+ 'SVTRRecResizeImg']['image_shape']
+ elif arch_config["algorithm"].lower() == "ABINet".lower():
+ rec_rs = [c for c in config["Eval"]["dataset"]["transforms"] if 'ABINetRecResizeImg' in c]
+ input_shape = rec_rs[0]['ABINetRecResizeImg']['image_shape'] if rec_rs else None
+ else:
+ input_shape = None
+
+ if arch_config["algorithm"] in ["Distillation", ]: # distillation model
+ archs = list(arch_config["Models"].values())
+ for idx, name in enumerate(model.model_name_list):
+ sub_model_save_path = os.path.join(save_path, name, "inference")
+ export_single_model(model.model_list[idx], archs[idx],
+ sub_model_save_path, logger)
+ else:
+ save_path = os.path.join(save_path, "inference")
+ export_single_model(
+ model, arch_config, save_path, logger, input_shape=input_shape)
+
+
+if __name__ == "__main__":
+ main()
diff --git a/ocr-studio/PaddleOCR/tools/infer/predict_cls.py b/ocr-studio/PaddleOCR/tools/infer/predict_cls.py
new file mode 100644
index 0000000000000000000000000000000000000000..d2b7108ca35666acfa53e785686fd7b9dfc21ed5
--- /dev/null
+++ b/ocr-studio/PaddleOCR/tools/infer/predict_cls.py
@@ -0,0 +1,151 @@
+# Copyright (c) 2020 PaddlePaddle Authors. All Rights Reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+import os
+import sys
+
+__dir__ = os.path.dirname(os.path.abspath(__file__))
+sys.path.append(__dir__)
+sys.path.insert(0, os.path.abspath(os.path.join(__dir__, '../..')))
+
+os.environ["FLAGS_allocator_strategy"] = 'auto_growth'
+
+import cv2
+import copy
+import numpy as np
+import math
+import time
+import traceback
+
+import tools.infer.utility as utility
+from ppocr.postprocess import build_post_process
+from ppocr.utils.logging import get_logger
+from ppocr.utils.utility import get_image_file_list, check_and_read
+
+logger = get_logger()
+
+
+class TextClassifier(object):
+ def __init__(self, args):
+ self.cls_image_shape = [int(v) for v in args.cls_image_shape.split(",")]
+ self.cls_batch_num = args.cls_batch_num
+ self.cls_thresh = args.cls_thresh
+ postprocess_params = {
+ 'name': 'ClsPostProcess',
+ "label_list": args.label_list,
+ }
+ self.postprocess_op = build_post_process(postprocess_params)
+ self.predictor, self.input_tensor, self.output_tensors, _ = \
+ utility.create_predictor(args, 'cls', logger)
+ self.use_onnx = args.use_onnx
+
+ def resize_norm_img(self, img):
+ imgC, imgH, imgW = self.cls_image_shape
+ h = img.shape[0]
+ w = img.shape[1]
+ ratio = w / float(h)
+ if math.ceil(imgH * ratio) > imgW:
+ resized_w = imgW
+ else:
+ resized_w = int(math.ceil(imgH * ratio))
+ resized_image = cv2.resize(img, (resized_w, imgH))
+ resized_image = resized_image.astype('float32')
+ if self.cls_image_shape[0] == 1:
+ resized_image = resized_image / 255
+ resized_image = resized_image[np.newaxis, :]
+ else:
+ resized_image = resized_image.transpose((2, 0, 1)) / 255
+ resized_image -= 0.5
+ resized_image /= 0.5
+ padding_im = np.zeros((imgC, imgH, imgW), dtype=np.float32)
+ padding_im[:, :, 0:resized_w] = resized_image
+ return padding_im
+
+ def __call__(self, img_list):
+ img_list = copy.deepcopy(img_list)
+ img_num = len(img_list)
+ # Calculate the aspect ratio of all text bars
+ width_list = []
+ for img in img_list:
+ width_list.append(img.shape[1] / float(img.shape[0]))
+ # Sorting can speed up the cls process
+ indices = np.argsort(np.array(width_list))
+
+ cls_res = [['', 0.0]] * img_num
+ batch_num = self.cls_batch_num
+ elapse = 0
+ for beg_img_no in range(0, img_num, batch_num):
+
+ end_img_no = min(img_num, beg_img_no + batch_num)
+ norm_img_batch = []
+ max_wh_ratio = 0
+ starttime = time.time()
+ for ino in range(beg_img_no, end_img_no):
+ h, w = img_list[indices[ino]].shape[0:2]
+ wh_ratio = w * 1.0 / h
+ max_wh_ratio = max(max_wh_ratio, wh_ratio)
+ for ino in range(beg_img_no, end_img_no):
+ norm_img = self.resize_norm_img(img_list[indices[ino]])
+ norm_img = norm_img[np.newaxis, :]
+ norm_img_batch.append(norm_img)
+ norm_img_batch = np.concatenate(norm_img_batch)
+ norm_img_batch = norm_img_batch.copy()
+
+ if self.use_onnx:
+ input_dict = {}
+ input_dict[self.input_tensor.name] = norm_img_batch
+ outputs = self.predictor.run(self.output_tensors, input_dict)
+ prob_out = outputs[0]
+ else:
+ self.input_tensor.copy_from_cpu(norm_img_batch)
+ self.predictor.run()
+ prob_out = self.output_tensors[0].copy_to_cpu()
+ self.predictor.try_shrink_memory()
+ cls_result = self.postprocess_op(prob_out)
+ elapse += time.time() - starttime
+ for rno in range(len(cls_result)):
+ label, score = cls_result[rno]
+ cls_res[indices[beg_img_no + rno]] = [label, score]
+ if '180' in label and score > self.cls_thresh:
+ img_list[indices[beg_img_no + rno]] = cv2.rotate(
+ img_list[indices[beg_img_no + rno]], 1)
+ return img_list, cls_res, elapse
+
+
+def main(args):
+ image_file_list = get_image_file_list(args.image_dir)
+ text_classifier = TextClassifier(args)
+ valid_image_file_list = []
+ img_list = []
+ for image_file in image_file_list:
+ img, flag, _ = check_and_read(image_file)
+ if not flag:
+ img = cv2.imread(image_file)
+ if img is None:
+ logger.info("error in loading image:{}".format(image_file))
+ continue
+ valid_image_file_list.append(image_file)
+ img_list.append(img)
+ try:
+ img_list, cls_res, predict_time = text_classifier(img_list)
+ except Exception as E:
+ logger.info(traceback.format_exc())
+ logger.info(E)
+ exit()
+ for ino in range(len(img_list)):
+ logger.info("Predicts of {}:{}".format(valid_image_file_list[ino],
+ cls_res[ino]))
+
+
+if __name__ == "__main__":
+ main(utility.parse_args())
diff --git a/ocr-studio/PaddleOCR/tools/infer/predict_det.py b/ocr-studio/PaddleOCR/tools/infer/predict_det.py
new file mode 100644
index 0000000000000000000000000000000000000000..6c5c36cf86febef406609bf5022cfd2ee776756f
--- /dev/null
+++ b/ocr-studio/PaddleOCR/tools/infer/predict_det.py
@@ -0,0 +1,355 @@
+# Copyright (c) 2020 PaddlePaddle Authors. All Rights Reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+import os
+import sys
+
+__dir__ = os.path.dirname(os.path.abspath(__file__))
+sys.path.append(__dir__)
+sys.path.insert(0, os.path.abspath(os.path.join(__dir__, '../..')))
+
+os.environ["FLAGS_allocator_strategy"] = 'auto_growth'
+
+import cv2
+import numpy as np
+import time
+import sys
+
+import tools.infer.utility as utility
+from ppocr.utils.logging import get_logger
+from ppocr.utils.utility import get_image_file_list, check_and_read
+from ppocr.data import create_operators, transform
+from ppocr.postprocess import build_post_process
+import json
+logger = get_logger()
+
+
+class TextDetector(object):
+ def __init__(self, args):
+ self.args = args
+ self.det_algorithm = args.det_algorithm
+ self.use_onnx = args.use_onnx
+ pre_process_list = [{
+ 'DetResizeForTest': {
+ 'limit_side_len': args.det_limit_side_len,
+ 'limit_type': args.det_limit_type,
+ }
+ }, {
+ 'NormalizeImage': {
+ 'std': [0.229, 0.224, 0.225],
+ 'mean': [0.485, 0.456, 0.406],
+ 'scale': '1./255.',
+ 'order': 'hwc'
+ }
+ }, {
+ 'ToCHWImage': None
+ }, {
+ 'KeepKeys': {
+ 'keep_keys': ['image', 'shape']
+ }
+ }]
+ postprocess_params = {}
+ if self.det_algorithm == "DB":
+ postprocess_params['name'] = 'DBPostProcess'
+ postprocess_params["thresh"] = args.det_db_thresh
+ postprocess_params["box_thresh"] = args.det_db_box_thresh
+ postprocess_params["max_candidates"] = 1000
+ postprocess_params["unclip_ratio"] = args.det_db_unclip_ratio
+ postprocess_params["use_dilation"] = args.use_dilation
+ postprocess_params["score_mode"] = args.det_db_score_mode
+ postprocess_params["box_type"] = args.det_box_type
+ elif self.det_algorithm == "DB++":
+ postprocess_params['name'] = 'DBPostProcess'
+ postprocess_params["thresh"] = args.det_db_thresh
+ postprocess_params["box_thresh"] = args.det_db_box_thresh
+ postprocess_params["max_candidates"] = 1000
+ postprocess_params["unclip_ratio"] = args.det_db_unclip_ratio
+ postprocess_params["use_dilation"] = args.use_dilation
+ postprocess_params["score_mode"] = args.det_db_score_mode
+ postprocess_params["box_type"] = args.det_box_type
+ pre_process_list[1] = {
+ 'NormalizeImage': {
+ 'std': [1.0, 1.0, 1.0],
+ 'mean':
+ [0.48109378172549, 0.45752457890196, 0.40787054090196],
+ 'scale': '1./255.',
+ 'order': 'hwc'
+ }
+ }
+ elif self.det_algorithm == "EAST":
+ postprocess_params['name'] = 'EASTPostProcess'
+ postprocess_params["score_thresh"] = args.det_east_score_thresh
+ postprocess_params["cover_thresh"] = args.det_east_cover_thresh
+ postprocess_params["nms_thresh"] = args.det_east_nms_thresh
+ elif self.det_algorithm == "SAST":
+ pre_process_list[0] = {
+ 'DetResizeForTest': {
+ 'resize_long': args.det_limit_side_len
+ }
+ }
+ postprocess_params['name'] = 'SASTPostProcess'
+ postprocess_params["score_thresh"] = args.det_sast_score_thresh
+ postprocess_params["nms_thresh"] = args.det_sast_nms_thresh
+
+ if args.det_box_type == 'poly':
+ postprocess_params["sample_pts_num"] = 6
+ postprocess_params["expand_scale"] = 1.2
+ postprocess_params["shrink_ratio_of_width"] = 0.2
+ else:
+ postprocess_params["sample_pts_num"] = 2
+ postprocess_params["expand_scale"] = 1.0
+ postprocess_params["shrink_ratio_of_width"] = 0.3
+
+ elif self.det_algorithm == "PSE":
+ postprocess_params['name'] = 'PSEPostProcess'
+ postprocess_params["thresh"] = args.det_pse_thresh
+ postprocess_params["box_thresh"] = args.det_pse_box_thresh
+ postprocess_params["min_area"] = args.det_pse_min_area
+ postprocess_params["box_type"] = args.det_box_type
+ postprocess_params["scale"] = args.det_pse_scale
+ elif self.det_algorithm == "FCE":
+ pre_process_list[0] = {
+ 'DetResizeForTest': {
+ 'rescale_img': [1080, 736]
+ }
+ }
+ postprocess_params['name'] = 'FCEPostProcess'
+ postprocess_params["scales"] = args.scales
+ postprocess_params["alpha"] = args.alpha
+ postprocess_params["beta"] = args.beta
+ postprocess_params["fourier_degree"] = args.fourier_degree
+ postprocess_params["box_type"] = args.det_box_type
+ elif self.det_algorithm == "CT":
+ pre_process_list[0] = {'ScaleAlignedShort': {'short_size': 640}}
+ postprocess_params['name'] = 'CTPostProcess'
+ else:
+ logger.info("unknown det_algorithm:{}".format(self.det_algorithm))
+ sys.exit(0)
+
+ self.preprocess_op = create_operators(pre_process_list)
+ self.postprocess_op = build_post_process(postprocess_params)
+ self.predictor, self.input_tensor, self.output_tensors, self.config = utility.create_predictor(
+ args, 'det', logger)
+
+ if self.use_onnx:
+ img_h, img_w = self.input_tensor.shape[2:]
+ if isinstance(img_h, str) or isinstance(img_w, str):
+ pass
+ elif img_h is not None and img_w is not None and img_h > 0 and img_w > 0:
+ pre_process_list[0] = {
+ 'DetResizeForTest': {
+ 'image_shape': [img_h, img_w]
+ }
+ }
+ self.preprocess_op = create_operators(pre_process_list)
+
+ if args.benchmark:
+ import auto_log
+ pid = os.getpid()
+ gpu_id = utility.get_infer_gpuid()
+ self.autolog = auto_log.AutoLogger(
+ model_name="det",
+ model_precision=args.precision,
+ batch_size=1,
+ data_shape="dynamic",
+ save_path=None,
+ inference_config=self.config,
+ pids=pid,
+ process_name=None,
+ gpu_ids=gpu_id if args.use_gpu else None,
+ time_keys=[
+ 'preprocess_time', 'inference_time', 'postprocess_time'
+ ],
+ warmup=2,
+ logger=logger)
+
+ def order_points_clockwise(self, pts):
+ rect = np.zeros((4, 2), dtype="float32")
+ s = pts.sum(axis=1)
+ rect[0] = pts[np.argmin(s)]
+ rect[2] = pts[np.argmax(s)]
+ tmp = np.delete(pts, (np.argmin(s), np.argmax(s)), axis=0)
+ diff = np.diff(np.array(tmp), axis=1)
+ rect[1] = tmp[np.argmin(diff)]
+ rect[3] = tmp[np.argmax(diff)]
+ return rect
+
+ def clip_det_res(self, points, img_height, img_width):
+ for pno in range(points.shape[0]):
+ points[pno, 0] = int(min(max(points[pno, 0], 0), img_width - 1))
+ points[pno, 1] = int(min(max(points[pno, 1], 0), img_height - 1))
+ return points
+
+ def filter_tag_det_res(self, dt_boxes, image_shape):
+ img_height, img_width = image_shape[0:2]
+ dt_boxes_new = []
+ for box in dt_boxes:
+ if type(box) is list:
+ box = np.array(box)
+ box = self.order_points_clockwise(box)
+ box = self.clip_det_res(box, img_height, img_width)
+ rect_width = int(np.linalg.norm(box[0] - box[1]))
+ rect_height = int(np.linalg.norm(box[0] - box[3]))
+ if rect_width <= 3 or rect_height <= 3:
+ continue
+ dt_boxes_new.append(box)
+ dt_boxes = np.array(dt_boxes_new)
+ return dt_boxes
+
+ def filter_tag_det_res_only_clip(self, dt_boxes, image_shape):
+ img_height, img_width = image_shape[0:2]
+ dt_boxes_new = []
+ for box in dt_boxes:
+ if type(box) is list:
+ box = np.array(box)
+ box = self.clip_det_res(box, img_height, img_width)
+ dt_boxes_new.append(box)
+ dt_boxes = np.array(dt_boxes_new)
+ return dt_boxes
+
+ def __call__(self, img):
+ ori_im = img.copy()
+ data = {'image': img}
+
+ st = time.time()
+
+ if self.args.benchmark:
+ self.autolog.times.start()
+
+ data = transform(data, self.preprocess_op)
+ img, shape_list = data
+ if img is None:
+ return None, 0
+ img = np.expand_dims(img, axis=0)
+ shape_list = np.expand_dims(shape_list, axis=0)
+ img = img.copy()
+
+ if self.args.benchmark:
+ self.autolog.times.stamp()
+ if self.use_onnx:
+ input_dict = {}
+ input_dict[self.input_tensor.name] = img
+ outputs = self.predictor.run(self.output_tensors, input_dict)
+ else:
+ self.input_tensor.copy_from_cpu(img)
+ self.predictor.run()
+ outputs = []
+ for output_tensor in self.output_tensors:
+ output = output_tensor.copy_to_cpu()
+ outputs.append(output)
+ if self.args.benchmark:
+ self.autolog.times.stamp()
+
+ preds = {}
+ if self.det_algorithm == "EAST":
+ preds['f_geo'] = outputs[0]
+ preds['f_score'] = outputs[1]
+ elif self.det_algorithm == 'SAST':
+ preds['f_border'] = outputs[0]
+ preds['f_score'] = outputs[1]
+ preds['f_tco'] = outputs[2]
+ preds['f_tvo'] = outputs[3]
+ elif self.det_algorithm in ['DB', 'PSE', 'DB++']:
+ preds['maps'] = outputs[0]
+ elif self.det_algorithm == 'FCE':
+ for i, output in enumerate(outputs):
+ preds['level_{}'.format(i)] = output
+ elif self.det_algorithm == "CT":
+ preds['maps'] = outputs[0]
+ preds['score'] = outputs[1]
+ else:
+ raise NotImplementedError
+
+ post_result = self.postprocess_op(preds, shape_list)
+ dt_boxes = post_result[0]['points']
+
+ if self.args.det_box_type == 'poly':
+ dt_boxes = self.filter_tag_det_res_only_clip(dt_boxes, ori_im.shape)
+ else:
+ dt_boxes = self.filter_tag_det_res(dt_boxes, ori_im.shape)
+
+ if self.args.benchmark:
+ self.autolog.times.end(stamp=True)
+ et = time.time()
+ return dt_boxes, et - st
+
+
+if __name__ == "__main__":
+ args = utility.parse_args()
+ image_file_list = get_image_file_list(args.image_dir)
+ text_detector = TextDetector(args)
+ total_time = 0
+ draw_img_save_dir = args.draw_img_save_dir
+ os.makedirs(draw_img_save_dir, exist_ok=True)
+
+ if args.warmup:
+ img = np.random.uniform(0, 255, [640, 640, 3]).astype(np.uint8)
+ for i in range(2):
+ res = text_detector(img)
+
+ save_results = []
+ for idx, image_file in enumerate(image_file_list):
+ img, flag_gif, flag_pdf = check_and_read(image_file)
+ if not flag_gif and not flag_pdf:
+ img = cv2.imread(image_file)
+ if not flag_pdf:
+ if img is None:
+ logger.debug("error in loading image:{}".format(image_file))
+ continue
+ imgs = [img]
+ else:
+ page_num = args.page_num
+ if page_num > len(img) or page_num == 0:
+ page_num = len(img)
+ imgs = img[:page_num]
+ for index, img in enumerate(imgs):
+ st = time.time()
+ dt_boxes, _ = text_detector(img)
+ elapse = time.time() - st
+ total_time += elapse
+ if len(imgs) > 1:
+ save_pred = os.path.basename(image_file) + '_' + str(
+ index) + "\t" + str(
+ json.dumps([x.tolist() for x in dt_boxes])) + "\n"
+ else:
+ save_pred = os.path.basename(image_file) + "\t" + str(
+ json.dumps([x.tolist() for x in dt_boxes])) + "\n"
+ save_results.append(save_pred)
+ logger.info(save_pred)
+ if len(imgs) > 1:
+ logger.info("{}_{} The predict time of {}: {}".format(
+ idx, index, image_file, elapse))
+ else:
+ logger.info("{} The predict time of {}: {}".format(
+ idx, image_file, elapse))
+
+ src_im = utility.draw_text_det_res(dt_boxes, img)
+
+ if flag_gif:
+ save_file = image_file[:-3] + "png"
+ elif flag_pdf:
+ save_file = image_file.replace('.pdf',
+ '_' + str(index) + '.png')
+ else:
+ save_file = image_file
+ img_path = os.path.join(
+ draw_img_save_dir,
+ "det_res_{}".format(os.path.basename(save_file)))
+ cv2.imwrite(img_path, src_im)
+ logger.info("The visualized image saved in {}".format(img_path))
+
+ with open(os.path.join(draw_img_save_dir, "det_results.txt"), 'w') as f:
+ f.writelines(save_results)
+ f.close()
+ if args.benchmark:
+ text_detector.autolog.report()
diff --git a/ocr-studio/PaddleOCR/tools/infer/predict_e2e.py b/ocr-studio/PaddleOCR/tools/infer/predict_e2e.py
new file mode 100644
index 0000000000000000000000000000000000000000..de315d701c7172ded4d30e48e79abee367f42239
--- /dev/null
+++ b/ocr-studio/PaddleOCR/tools/infer/predict_e2e.py
@@ -0,0 +1,169 @@
+# Copyright (c) 2020 PaddlePaddle Authors. All Rights Reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+import os
+import sys
+
+__dir__ = os.path.dirname(os.path.abspath(__file__))
+sys.path.append(__dir__)
+sys.path.insert(0, os.path.abspath(os.path.join(__dir__, '../..')))
+
+os.environ["FLAGS_allocator_strategy"] = 'auto_growth'
+
+import cv2
+import numpy as np
+import time
+import sys
+
+import tools.infer.utility as utility
+from ppocr.utils.logging import get_logger
+from ppocr.utils.utility import get_image_file_list, check_and_read
+from ppocr.data import create_operators, transform
+from ppocr.postprocess import build_post_process
+
+logger = get_logger()
+
+
+class TextE2E(object):
+ def __init__(self, args):
+ self.args = args
+ self.e2e_algorithm = args.e2e_algorithm
+ self.use_onnx = args.use_onnx
+ pre_process_list = [{
+ 'E2EResizeForTest': {}
+ }, {
+ 'NormalizeImage': {
+ 'std': [0.229, 0.224, 0.225],
+ 'mean': [0.485, 0.456, 0.406],
+ 'scale': '1./255.',
+ 'order': 'hwc'
+ }
+ }, {
+ 'ToCHWImage': None
+ }, {
+ 'KeepKeys': {
+ 'keep_keys': ['image', 'shape']
+ }
+ }]
+ postprocess_params = {}
+ if self.e2e_algorithm == "PGNet":
+ pre_process_list[0] = {
+ 'E2EResizeForTest': {
+ 'max_side_len': args.e2e_limit_side_len,
+ 'valid_set': 'totaltext'
+ }
+ }
+ postprocess_params['name'] = 'PGPostProcess'
+ postprocess_params["score_thresh"] = args.e2e_pgnet_score_thresh
+ postprocess_params["character_dict_path"] = args.e2e_char_dict_path
+ postprocess_params["valid_set"] = args.e2e_pgnet_valid_set
+ postprocess_params["mode"] = args.e2e_pgnet_mode
+ else:
+ logger.info("unknown e2e_algorithm:{}".format(self.e2e_algorithm))
+ sys.exit(0)
+
+ self.preprocess_op = create_operators(pre_process_list)
+ self.postprocess_op = build_post_process(postprocess_params)
+ self.predictor, self.input_tensor, self.output_tensors, _ = utility.create_predictor(
+ args, 'e2e', logger) # paddle.jit.load(args.det_model_dir)
+ # self.predictor.eval()
+
+ def clip_det_res(self, points, img_height, img_width):
+ for pno in range(points.shape[0]):
+ points[pno, 0] = int(min(max(points[pno, 0], 0), img_width - 1))
+ points[pno, 1] = int(min(max(points[pno, 1], 0), img_height - 1))
+ return points
+
+ def filter_tag_det_res_only_clip(self, dt_boxes, image_shape):
+ img_height, img_width = image_shape[0:2]
+ dt_boxes_new = []
+ for box in dt_boxes:
+ box = self.clip_det_res(box, img_height, img_width)
+ dt_boxes_new.append(box)
+ dt_boxes = np.array(dt_boxes_new)
+ return dt_boxes
+
+ def __call__(self, img):
+
+ ori_im = img.copy()
+ data = {'image': img}
+ data = transform(data, self.preprocess_op)
+ img, shape_list = data
+ if img is None:
+ return None, 0
+ img = np.expand_dims(img, axis=0)
+ shape_list = np.expand_dims(shape_list, axis=0)
+ img = img.copy()
+ starttime = time.time()
+
+ if self.use_onnx:
+ input_dict = {}
+ input_dict[self.input_tensor.name] = img
+ outputs = self.predictor.run(self.output_tensors, input_dict)
+ preds = {}
+ preds['f_border'] = outputs[0]
+ preds['f_char'] = outputs[1]
+ preds['f_direction'] = outputs[2]
+ preds['f_score'] = outputs[3]
+ else:
+ self.input_tensor.copy_from_cpu(img)
+ self.predictor.run()
+ outputs = []
+ for output_tensor in self.output_tensors:
+ output = output_tensor.copy_to_cpu()
+ outputs.append(output)
+
+ preds = {}
+ if self.e2e_algorithm == 'PGNet':
+ preds['f_border'] = outputs[0]
+ preds['f_char'] = outputs[1]
+ preds['f_direction'] = outputs[2]
+ preds['f_score'] = outputs[3]
+ else:
+ raise NotImplementedError
+ post_result = self.postprocess_op(preds, shape_list)
+ points, strs = post_result['points'], post_result['texts']
+ dt_boxes = self.filter_tag_det_res_only_clip(points, ori_im.shape)
+ elapse = time.time() - starttime
+ return dt_boxes, strs, elapse
+
+
+if __name__ == "__main__":
+ args = utility.parse_args()
+ image_file_list = get_image_file_list(args.image_dir)
+ text_detector = TextE2E(args)
+ count = 0
+ total_time = 0
+ draw_img_save = "./inference_results"
+ if not os.path.exists(draw_img_save):
+ os.makedirs(draw_img_save)
+ for image_file in image_file_list:
+ img, flag, _ = check_and_read(image_file)
+ if not flag:
+ img = cv2.imread(image_file)
+ if img is None:
+ logger.info("error in loading image:{}".format(image_file))
+ continue
+ points, strs, elapse = text_detector(img)
+ if count > 0:
+ total_time += elapse
+ count += 1
+ logger.info("Predict time of {}: {}".format(image_file, elapse))
+ src_im = utility.draw_e2e_res(points, strs, image_file)
+ img_name_pure = os.path.split(image_file)[-1]
+ img_path = os.path.join(draw_img_save,
+ "e2e_res_{}".format(img_name_pure))
+ cv2.imwrite(img_path, src_im)
+ logger.info("The visualized image saved in {}".format(img_path))
+ if count > 1:
+ logger.info("Avg Time: {}".format(total_time / (count - 1)))
diff --git a/ocr-studio/PaddleOCR/tools/infer/predict_rec.py b/ocr-studio/PaddleOCR/tools/infer/predict_rec.py
new file mode 100644
index 0000000000000000000000000000000000000000..d168af6639094f7b0fe31926858b46c6f3a63928
--- /dev/null
+++ b/ocr-studio/PaddleOCR/tools/infer/predict_rec.py
@@ -0,0 +1,737 @@
+# Copyright (c) 2020 PaddlePaddle Authors. All Rights Reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+import os
+import sys
+from PIL import Image
+__dir__ = os.path.dirname(os.path.abspath(__file__))
+sys.path.append(__dir__)
+sys.path.insert(0, os.path.abspath(os.path.join(__dir__, '../..')))
+
+os.environ["FLAGS_allocator_strategy"] = 'auto_growth'
+
+import cv2
+import numpy as np
+import math
+import time
+import traceback
+import paddle
+
+import tools.infer.utility as utility
+from ppocr.postprocess import build_post_process
+from ppocr.utils.logging import get_logger
+from ppocr.utils.utility import get_image_file_list, check_and_read
+
+logger = get_logger()
+
+
+class TextRecognizer(object):
+ def __init__(self, args):
+ self.rec_image_shape = [int(v) for v in args.rec_image_shape.split(",")]
+ self.rec_batch_num = args.rec_batch_num
+ self.rec_algorithm = args.rec_algorithm
+ postprocess_params = {
+ 'name': 'CTCLabelDecode',
+ "character_dict_path": args.rec_char_dict_path,
+ "use_space_char": args.use_space_char
+ }
+ if self.rec_algorithm == "SRN":
+ postprocess_params = {
+ 'name': 'SRNLabelDecode',
+ "character_dict_path": args.rec_char_dict_path,
+ "use_space_char": args.use_space_char
+ }
+ elif self.rec_algorithm == "RARE":
+ postprocess_params = {
+ 'name': 'AttnLabelDecode',
+ "character_dict_path": args.rec_char_dict_path,
+ "use_space_char": args.use_space_char
+ }
+ elif self.rec_algorithm == 'NRTR':
+ postprocess_params = {
+ 'name': 'NRTRLabelDecode',
+ "character_dict_path": args.rec_char_dict_path,
+ "use_space_char": args.use_space_char
+ }
+ elif self.rec_algorithm == "SAR":
+ postprocess_params = {
+ 'name': 'SARLabelDecode',
+ "character_dict_path": args.rec_char_dict_path,
+ "use_space_char": args.use_space_char
+ }
+ elif self.rec_algorithm == "VisionLAN":
+ postprocess_params = {
+ 'name': 'VLLabelDecode',
+ "character_dict_path": args.rec_char_dict_path,
+ "use_space_char": args.use_space_char,
+ "max_text_length": args.max_text_length
+ }
+ elif self.rec_algorithm == 'ViTSTR':
+ postprocess_params = {
+ 'name': 'ViTSTRLabelDecode',
+ "character_dict_path": args.rec_char_dict_path,
+ "use_space_char": args.use_space_char
+ }
+ elif self.rec_algorithm == 'ABINet':
+ postprocess_params = {
+ 'name': 'ABINetLabelDecode',
+ "character_dict_path": args.rec_char_dict_path,
+ "use_space_char": args.use_space_char
+ }
+ elif self.rec_algorithm == "SPIN":
+ postprocess_params = {
+ 'name': 'SPINLabelDecode',
+ "character_dict_path": args.rec_char_dict_path,
+ "use_space_char": args.use_space_char
+ }
+ elif self.rec_algorithm == "RobustScanner":
+ postprocess_params = {
+ 'name': 'SARLabelDecode',
+ "character_dict_path": args.rec_char_dict_path,
+ "use_space_char": args.use_space_char,
+ "rm_symbol": True
+ }
+ elif self.rec_algorithm == 'RFL':
+ postprocess_params = {
+ 'name': 'RFLLabelDecode',
+ "character_dict_path": None,
+ "use_space_char": args.use_space_char
+ }
+ elif self.rec_algorithm == "SATRN":
+ postprocess_params = {
+ 'name': 'SATRNLabelDecode',
+ "character_dict_path": args.rec_char_dict_path,
+ "use_space_char": args.use_space_char,
+ "rm_symbol": True
+ }
+ elif self.rec_algorithm in ["CPPD", "CPPDPadding"]:
+ postprocess_params = {
+ 'name': 'CPPDLabelDecode',
+ "character_dict_path": args.rec_char_dict_path,
+ "use_space_char": args.use_space_char,
+ "rm_symbol": True
+ }
+ elif self.rec_algorithm == "PREN":
+ postprocess_params = {'name': 'PRENLabelDecode'}
+ elif self.rec_algorithm == "CAN":
+ self.inverse = args.rec_image_inverse
+ postprocess_params = {
+ 'name': 'CANLabelDecode',
+ "character_dict_path": args.rec_char_dict_path,
+ "use_space_char": args.use_space_char
+ }
+ elif self.rec_algorithm == "ParseQ":
+ postprocess_params = {
+ 'name': 'ParseQLabelDecode',
+ "character_dict_path": args.rec_char_dict_path,
+ "use_space_char": args.use_space_char
+ }
+ self.postprocess_op = build_post_process(postprocess_params)
+ self.postprocess_params = postprocess_params
+ self.predictor, self.input_tensor, self.output_tensors, self.config = \
+ utility.create_predictor(args, 'rec', logger)
+ self.benchmark = args.benchmark
+ self.use_onnx = args.use_onnx
+ if args.benchmark:
+ import auto_log
+ pid = os.getpid()
+ gpu_id = utility.get_infer_gpuid()
+ self.autolog = auto_log.AutoLogger(
+ model_name="rec",
+ model_precision=args.precision,
+ batch_size=args.rec_batch_num,
+ data_shape="dynamic",
+ save_path=None, #args.save_log_path,
+ inference_config=self.config,
+ pids=pid,
+ process_name=None,
+ gpu_ids=gpu_id if args.use_gpu else None,
+ time_keys=[
+ 'preprocess_time', 'inference_time', 'postprocess_time'
+ ],
+ warmup=0,
+ logger=logger)
+ self.return_word_box = args.return_word_box
+
+ def resize_norm_img(self, img, max_wh_ratio):
+ imgC, imgH, imgW = self.rec_image_shape
+ if self.rec_algorithm == 'NRTR' or self.rec_algorithm == 'ViTSTR':
+ img = cv2.cvtColor(img, cv2.COLOR_BGR2GRAY)
+ # return padding_im
+ image_pil = Image.fromarray(np.uint8(img))
+ if self.rec_algorithm == 'ViTSTR':
+ img = image_pil.resize([imgW, imgH], Image.BICUBIC)
+ else:
+ img = image_pil.resize([imgW, imgH], Image.Resampling.LANCZOS)
+ img = np.array(img)
+ norm_img = np.expand_dims(img, -1)
+ norm_img = norm_img.transpose((2, 0, 1))
+ if self.rec_algorithm == 'ViTSTR':
+ norm_img = norm_img.astype(np.float32) / 255.
+ else:
+ norm_img = norm_img.astype(np.float32) / 128. - 1.
+ return norm_img
+ elif self.rec_algorithm == 'RFL':
+ img = cv2.cvtColor(img, cv2.COLOR_BGR2GRAY)
+ resized_image = cv2.resize(
+ img, (imgW, imgH), interpolation=cv2.INTER_CUBIC)
+ resized_image = resized_image.astype('float32')
+ resized_image = resized_image / 255
+ resized_image = resized_image[np.newaxis, :]
+ resized_image -= 0.5
+ resized_image /= 0.5
+ return resized_image
+
+ assert imgC == img.shape[2]
+ imgW = int((imgH * max_wh_ratio))
+ if self.use_onnx:
+ w = self.input_tensor.shape[3:][0]
+ if isinstance(w, str):
+ pass
+ elif w is not None and w > 0:
+ imgW = w
+ h, w = img.shape[:2]
+ ratio = w / float(h)
+ if math.ceil(imgH * ratio) > imgW:
+ resized_w = imgW
+ else:
+ resized_w = int(math.ceil(imgH * ratio))
+ if self.rec_algorithm == 'RARE':
+ if resized_w > self.rec_image_shape[2]:
+ resized_w = self.rec_image_shape[2]
+ imgW = self.rec_image_shape[2]
+ resized_image = cv2.resize(img, (resized_w, imgH))
+ resized_image = resized_image.astype('float32')
+ resized_image = resized_image.transpose((2, 0, 1)) / 255
+ resized_image -= 0.5
+ resized_image /= 0.5
+ padding_im = np.zeros((imgC, imgH, imgW), dtype=np.float32)
+ padding_im[:, :, 0:resized_w] = resized_image
+ return padding_im
+
+ def resize_norm_img_vl(self, img, image_shape):
+
+ imgC, imgH, imgW = image_shape
+ img = img[:, :, ::-1] # bgr2rgb
+ resized_image = cv2.resize(
+ img, (imgW, imgH), interpolation=cv2.INTER_LINEAR)
+ resized_image = resized_image.astype('float32')
+ resized_image = resized_image.transpose((2, 0, 1)) / 255
+ return resized_image
+
+ def resize_norm_img_srn(self, img, image_shape):
+ imgC, imgH, imgW = image_shape
+
+ img_black = np.zeros((imgH, imgW))
+ im_hei = img.shape[0]
+ im_wid = img.shape[1]
+
+ if im_wid <= im_hei * 1:
+ img_new = cv2.resize(img, (imgH * 1, imgH))
+ elif im_wid <= im_hei * 2:
+ img_new = cv2.resize(img, (imgH * 2, imgH))
+ elif im_wid <= im_hei * 3:
+ img_new = cv2.resize(img, (imgH * 3, imgH))
+ else:
+ img_new = cv2.resize(img, (imgW, imgH))
+
+ img_np = np.asarray(img_new)
+ img_np = cv2.cvtColor(img_np, cv2.COLOR_BGR2GRAY)
+ img_black[:, 0:img_np.shape[1]] = img_np
+ img_black = img_black[:, :, np.newaxis]
+
+ row, col, c = img_black.shape
+ c = 1
+
+ return np.reshape(img_black, (c, row, col)).astype(np.float32)
+
+ def srn_other_inputs(self, image_shape, num_heads, max_text_length):
+
+ imgC, imgH, imgW = image_shape
+ feature_dim = int((imgH / 8) * (imgW / 8))
+
+ encoder_word_pos = np.array(range(0, feature_dim)).reshape(
+ (feature_dim, 1)).astype('int64')
+ gsrm_word_pos = np.array(range(0, max_text_length)).reshape(
+ (max_text_length, 1)).astype('int64')
+
+ gsrm_attn_bias_data = np.ones((1, max_text_length, max_text_length))
+ gsrm_slf_attn_bias1 = np.triu(gsrm_attn_bias_data, 1).reshape(
+ [-1, 1, max_text_length, max_text_length])
+ gsrm_slf_attn_bias1 = np.tile(
+ gsrm_slf_attn_bias1,
+ [1, num_heads, 1, 1]).astype('float32') * [-1e9]
+
+ gsrm_slf_attn_bias2 = np.tril(gsrm_attn_bias_data, -1).reshape(
+ [-1, 1, max_text_length, max_text_length])
+ gsrm_slf_attn_bias2 = np.tile(
+ gsrm_slf_attn_bias2,
+ [1, num_heads, 1, 1]).astype('float32') * [-1e9]
+
+ encoder_word_pos = encoder_word_pos[np.newaxis, :]
+ gsrm_word_pos = gsrm_word_pos[np.newaxis, :]
+
+ return [
+ encoder_word_pos, gsrm_word_pos, gsrm_slf_attn_bias1,
+ gsrm_slf_attn_bias2
+ ]
+
+ def process_image_srn(self, img, image_shape, num_heads, max_text_length):
+ norm_img = self.resize_norm_img_srn(img, image_shape)
+ norm_img = norm_img[np.newaxis, :]
+
+ [encoder_word_pos, gsrm_word_pos, gsrm_slf_attn_bias1, gsrm_slf_attn_bias2] = \
+ self.srn_other_inputs(image_shape, num_heads, max_text_length)
+
+ gsrm_slf_attn_bias1 = gsrm_slf_attn_bias1.astype(np.float32)
+ gsrm_slf_attn_bias2 = gsrm_slf_attn_bias2.astype(np.float32)
+ encoder_word_pos = encoder_word_pos.astype(np.int64)
+ gsrm_word_pos = gsrm_word_pos.astype(np.int64)
+
+ return (norm_img, encoder_word_pos, gsrm_word_pos, gsrm_slf_attn_bias1,
+ gsrm_slf_attn_bias2)
+
+ def resize_norm_img_sar(self, img, image_shape,
+ width_downsample_ratio=0.25):
+ imgC, imgH, imgW_min, imgW_max = image_shape
+ h = img.shape[0]
+ w = img.shape[1]
+ valid_ratio = 1.0
+ # make sure new_width is an integral multiple of width_divisor.
+ width_divisor = int(1 / width_downsample_ratio)
+ # resize
+ ratio = w / float(h)
+ resize_w = math.ceil(imgH * ratio)
+ if resize_w % width_divisor != 0:
+ resize_w = round(resize_w / width_divisor) * width_divisor
+ if imgW_min is not None:
+ resize_w = max(imgW_min, resize_w)
+ if imgW_max is not None:
+ valid_ratio = min(1.0, 1.0 * resize_w / imgW_max)
+ resize_w = min(imgW_max, resize_w)
+ resized_image = cv2.resize(img, (resize_w, imgH))
+ resized_image = resized_image.astype('float32')
+ # norm
+ if image_shape[0] == 1:
+ resized_image = resized_image / 255
+ resized_image = resized_image[np.newaxis, :]
+ else:
+ resized_image = resized_image.transpose((2, 0, 1)) / 255
+ resized_image -= 0.5
+ resized_image /= 0.5
+ resize_shape = resized_image.shape
+ padding_im = -1.0 * np.ones((imgC, imgH, imgW_max), dtype=np.float32)
+ padding_im[:, :, 0:resize_w] = resized_image
+ pad_shape = padding_im.shape
+
+ return padding_im, resize_shape, pad_shape, valid_ratio
+
+ def resize_norm_img_spin(self, img):
+ img = cv2.cvtColor(img, cv2.COLOR_BGR2GRAY)
+ # return padding_im
+ img = cv2.resize(img, tuple([100, 32]), cv2.INTER_CUBIC)
+ img = np.array(img, np.float32)
+ img = np.expand_dims(img, -1)
+ img = img.transpose((2, 0, 1))
+ mean = [127.5]
+ std = [127.5]
+ mean = np.array(mean, dtype=np.float32)
+ std = np.array(std, dtype=np.float32)
+ mean = np.float32(mean.reshape(1, -1))
+ stdinv = 1 / np.float32(std.reshape(1, -1))
+ img -= mean
+ img *= stdinv
+ return img
+
+ def resize_norm_img_svtr(self, img, image_shape):
+
+ imgC, imgH, imgW = image_shape
+ resized_image = cv2.resize(
+ img, (imgW, imgH), interpolation=cv2.INTER_LINEAR)
+ resized_image = resized_image.astype('float32')
+ resized_image = resized_image.transpose((2, 0, 1)) / 255
+ resized_image -= 0.5
+ resized_image /= 0.5
+ return resized_image
+
+ def resize_norm_img_cppd_padding(self,
+ img,
+ image_shape,
+ padding=True,
+ interpolation=cv2.INTER_LINEAR):
+ imgC, imgH, imgW = image_shape
+ h = img.shape[0]
+ w = img.shape[1]
+ if not padding:
+ resized_image = cv2.resize(
+ img, (imgW, imgH), interpolation=interpolation)
+ resized_w = imgW
+ else:
+ ratio = w / float(h)
+ if math.ceil(imgH * ratio) > imgW:
+ resized_w = imgW
+ else:
+ resized_w = int(math.ceil(imgH * ratio))
+ resized_image = cv2.resize(img, (resized_w, imgH))
+ resized_image = resized_image.astype('float32')
+ if image_shape[0] == 1:
+ resized_image = resized_image / 255
+ resized_image = resized_image[np.newaxis, :]
+ else:
+ resized_image = resized_image.transpose((2, 0, 1)) / 255
+ resized_image -= 0.5
+ resized_image /= 0.5
+ padding_im = np.zeros((imgC, imgH, imgW), dtype=np.float32)
+ padding_im[:, :, 0:resized_w] = resized_image
+
+ return padding_im
+
+ def resize_norm_img_abinet(self, img, image_shape):
+
+ imgC, imgH, imgW = image_shape
+
+ resized_image = cv2.resize(
+ img, (imgW, imgH), interpolation=cv2.INTER_LINEAR)
+ resized_image = resized_image.astype('float32')
+ resized_image = resized_image / 255.
+
+ mean = np.array([0.485, 0.456, 0.406])
+ std = np.array([0.229, 0.224, 0.225])
+ resized_image = (
+ resized_image - mean[None, None, ...]) / std[None, None, ...]
+ resized_image = resized_image.transpose((2, 0, 1))
+ resized_image = resized_image.astype('float32')
+
+ return resized_image
+
+ def norm_img_can(self, img, image_shape):
+
+ img = cv2.cvtColor(
+ img, cv2.COLOR_BGR2GRAY) # CAN only predict gray scale image
+
+ if self.inverse:
+ img = 255 - img
+
+ if self.rec_image_shape[0] == 1:
+ h, w = img.shape
+ _, imgH, imgW = self.rec_image_shape
+ if h < imgH or w < imgW:
+ padding_h = max(imgH - h, 0)
+ padding_w = max(imgW - w, 0)
+ img_padded = np.pad(img, ((0, padding_h), (0, padding_w)),
+ 'constant',
+ constant_values=(255))
+ img = img_padded
+
+ img = np.expand_dims(img, 0) / 255.0 # h,w,c -> c,h,w
+ img = img.astype('float32')
+
+ return img
+
+ def __call__(self, img_list):
+ img_num = len(img_list)
+ # Calculate the aspect ratio of all text bars
+ width_list = []
+ for img in img_list:
+ width_list.append(img.shape[1] / float(img.shape[0]))
+ # Sorting can speed up the recognition process
+ indices = np.argsort(np.array(width_list))
+ rec_res = [['', 0.0]] * img_num
+ batch_num = self.rec_batch_num
+ st = time.time()
+ if self.benchmark:
+ self.autolog.times.start()
+ for beg_img_no in range(0, img_num, batch_num):
+ end_img_no = min(img_num, beg_img_no + batch_num)
+ norm_img_batch = []
+ if self.rec_algorithm == "SRN":
+ encoder_word_pos_list = []
+ gsrm_word_pos_list = []
+ gsrm_slf_attn_bias1_list = []
+ gsrm_slf_attn_bias2_list = []
+ if self.rec_algorithm == "SAR":
+ valid_ratios = []
+ imgC, imgH, imgW = self.rec_image_shape[:3]
+ max_wh_ratio = imgW / imgH
+ wh_ratio_list = []
+ for ino in range(beg_img_no, end_img_no):
+ h, w = img_list[indices[ino]].shape[0:2]
+ wh_ratio = w * 1.0 / h
+ max_wh_ratio = max(max_wh_ratio, wh_ratio)
+ wh_ratio_list.append(wh_ratio)
+ for ino in range(beg_img_no, end_img_no):
+ if self.rec_algorithm == "SAR":
+ norm_img, _, _, valid_ratio = self.resize_norm_img_sar(
+ img_list[indices[ino]], self.rec_image_shape)
+ norm_img = norm_img[np.newaxis, :]
+ valid_ratio = np.expand_dims(valid_ratio, axis=0)
+ valid_ratios.append(valid_ratio)
+ norm_img_batch.append(norm_img)
+ elif self.rec_algorithm == "SRN":
+ norm_img = self.process_image_srn(
+ img_list[indices[ino]], self.rec_image_shape, 8, 25)
+ encoder_word_pos_list.append(norm_img[1])
+ gsrm_word_pos_list.append(norm_img[2])
+ gsrm_slf_attn_bias1_list.append(norm_img[3])
+ gsrm_slf_attn_bias2_list.append(norm_img[4])
+ norm_img_batch.append(norm_img[0])
+ elif self.rec_algorithm in ["SVTR", "SATRN", "ParseQ", "CPPD"]:
+ norm_img = self.resize_norm_img_svtr(img_list[indices[ino]],
+ self.rec_image_shape)
+ norm_img = norm_img[np.newaxis, :]
+ norm_img_batch.append(norm_img)
+ elif self.rec_algorithm in ["CPPDPadding"]:
+ norm_img = self.resize_norm_img_cppd_padding(
+ img_list[indices[ino]], self.rec_image_shape)
+ norm_img = norm_img[np.newaxis, :]
+ norm_img_batch.append(norm_img)
+ elif self.rec_algorithm in ["VisionLAN", "PREN"]:
+ norm_img = self.resize_norm_img_vl(img_list[indices[ino]],
+ self.rec_image_shape)
+ norm_img = norm_img[np.newaxis, :]
+ norm_img_batch.append(norm_img)
+ elif self.rec_algorithm == 'SPIN':
+ norm_img = self.resize_norm_img_spin(img_list[indices[ino]])
+ norm_img = norm_img[np.newaxis, :]
+ norm_img_batch.append(norm_img)
+ elif self.rec_algorithm == "ABINet":
+ norm_img = self.resize_norm_img_abinet(
+ img_list[indices[ino]], self.rec_image_shape)
+ norm_img = norm_img[np.newaxis, :]
+ norm_img_batch.append(norm_img)
+ elif self.rec_algorithm == "RobustScanner":
+ norm_img, _, _, valid_ratio = self.resize_norm_img_sar(
+ img_list[indices[ino]],
+ self.rec_image_shape,
+ width_downsample_ratio=0.25)
+ norm_img = norm_img[np.newaxis, :]
+ valid_ratio = np.expand_dims(valid_ratio, axis=0)
+ valid_ratios = []
+ valid_ratios.append(valid_ratio)
+ norm_img_batch.append(norm_img)
+ word_positions_list = []
+ word_positions = np.array(range(0, 40)).astype('int64')
+ word_positions = np.expand_dims(word_positions, axis=0)
+ word_positions_list.append(word_positions)
+ elif self.rec_algorithm == "CAN":
+ norm_img = self.norm_img_can(img_list[indices[ino]],
+ max_wh_ratio)
+ norm_img = norm_img[np.newaxis, :]
+ norm_img_batch.append(norm_img)
+ norm_image_mask = np.ones(norm_img.shape, dtype='float32')
+ word_label = np.ones([1, 36], dtype='int64')
+ norm_img_mask_batch = []
+ word_label_list = []
+ norm_img_mask_batch.append(norm_image_mask)
+ word_label_list.append(word_label)
+ else:
+ norm_img = self.resize_norm_img(img_list[indices[ino]],
+ max_wh_ratio)
+ norm_img = norm_img[np.newaxis, :]
+ norm_img_batch.append(norm_img)
+ norm_img_batch = np.concatenate(norm_img_batch)
+ norm_img_batch = norm_img_batch.copy()
+ if self.benchmark:
+ self.autolog.times.stamp()
+
+ if self.rec_algorithm == "SRN":
+ encoder_word_pos_list = np.concatenate(encoder_word_pos_list)
+ gsrm_word_pos_list = np.concatenate(gsrm_word_pos_list)
+ gsrm_slf_attn_bias1_list = np.concatenate(
+ gsrm_slf_attn_bias1_list)
+ gsrm_slf_attn_bias2_list = np.concatenate(
+ gsrm_slf_attn_bias2_list)
+
+ inputs = [
+ norm_img_batch,
+ encoder_word_pos_list,
+ gsrm_word_pos_list,
+ gsrm_slf_attn_bias1_list,
+ gsrm_slf_attn_bias2_list,
+ ]
+ if self.use_onnx:
+ input_dict = {}
+ input_dict[self.input_tensor.name] = norm_img_batch
+ outputs = self.predictor.run(self.output_tensors,
+ input_dict)
+ preds = {"predict": outputs[2]}
+ else:
+ input_names = self.predictor.get_input_names()
+ for i in range(len(input_names)):
+ input_tensor = self.predictor.get_input_handle(
+ input_names[i])
+ input_tensor.copy_from_cpu(inputs[i])
+ self.predictor.run()
+ outputs = []
+ for output_tensor in self.output_tensors:
+ output = output_tensor.copy_to_cpu()
+ outputs.append(output)
+ if self.benchmark:
+ self.autolog.times.stamp()
+ preds = {"predict": outputs[2]}
+ elif self.rec_algorithm == "SAR":
+ valid_ratios = np.concatenate(valid_ratios)
+ inputs = [
+ norm_img_batch,
+ np.array(
+ [valid_ratios], dtype=np.float32),
+ ]
+ if self.use_onnx:
+ input_dict = {}
+ input_dict[self.input_tensor.name] = norm_img_batch
+ outputs = self.predictor.run(self.output_tensors,
+ input_dict)
+ preds = outputs[0]
+ else:
+ input_names = self.predictor.get_input_names()
+ for i in range(len(input_names)):
+ input_tensor = self.predictor.get_input_handle(
+ input_names[i])
+ input_tensor.copy_from_cpu(inputs[i])
+ self.predictor.run()
+ outputs = []
+ for output_tensor in self.output_tensors:
+ output = output_tensor.copy_to_cpu()
+ outputs.append(output)
+ if self.benchmark:
+ self.autolog.times.stamp()
+ preds = outputs[0]
+ elif self.rec_algorithm == "RobustScanner":
+ valid_ratios = np.concatenate(valid_ratios)
+ word_positions_list = np.concatenate(word_positions_list)
+ inputs = [norm_img_batch, valid_ratios, word_positions_list]
+
+ if self.use_onnx:
+ input_dict = {}
+ input_dict[self.input_tensor.name] = norm_img_batch
+ outputs = self.predictor.run(self.output_tensors,
+ input_dict)
+ preds = outputs[0]
+ else:
+ input_names = self.predictor.get_input_names()
+ for i in range(len(input_names)):
+ input_tensor = self.predictor.get_input_handle(
+ input_names[i])
+ input_tensor.copy_from_cpu(inputs[i])
+ self.predictor.run()
+ outputs = []
+ for output_tensor in self.output_tensors:
+ output = output_tensor.copy_to_cpu()
+ outputs.append(output)
+ if self.benchmark:
+ self.autolog.times.stamp()
+ preds = outputs[0]
+ elif self.rec_algorithm == "CAN":
+ norm_img_mask_batch = np.concatenate(norm_img_mask_batch)
+ word_label_list = np.concatenate(word_label_list)
+ inputs = [norm_img_batch, norm_img_mask_batch, word_label_list]
+ if self.use_onnx:
+ input_dict = {}
+ input_dict[self.input_tensor.name] = norm_img_batch
+ outputs = self.predictor.run(self.output_tensors,
+ input_dict)
+ preds = outputs
+ else:
+ input_names = self.predictor.get_input_names()
+ input_tensor = []
+ for i in range(len(input_names)):
+ input_tensor_i = self.predictor.get_input_handle(
+ input_names[i])
+ input_tensor_i.copy_from_cpu(inputs[i])
+ input_tensor.append(input_tensor_i)
+ self.input_tensor = input_tensor
+ self.predictor.run()
+ outputs = []
+ for output_tensor in self.output_tensors:
+ output = output_tensor.copy_to_cpu()
+ outputs.append(output)
+ if self.benchmark:
+ self.autolog.times.stamp()
+ preds = outputs
+ else:
+ if self.use_onnx:
+ input_dict = {}
+ input_dict[self.input_tensor.name] = norm_img_batch
+ outputs = self.predictor.run(self.output_tensors,
+ input_dict)
+ preds = outputs[0]
+ else:
+ self.input_tensor.copy_from_cpu(norm_img_batch)
+ self.predictor.run()
+ outputs = []
+ for output_tensor in self.output_tensors:
+ output = output_tensor.copy_to_cpu()
+ outputs.append(output)
+ if self.benchmark:
+ self.autolog.times.stamp()
+ if len(outputs) != 1:
+ preds = outputs
+ else:
+ preds = outputs[0]
+ self.predictor.try_shrink_memory()
+ if self.postprocess_params['name'] == 'CTCLabelDecode':
+ rec_result = self.postprocess_op(
+ preds,
+ return_word_box=self.return_word_box,
+ wh_ratio_list=wh_ratio_list,
+ max_wh_ratio=max_wh_ratio)
+ else:
+ rec_result = self.postprocess_op(preds)
+ for rno in range(len(rec_result)):
+ rec_res[indices[beg_img_no + rno]] = rec_result[rno]
+ if self.benchmark:
+ self.autolog.times.end(stamp=True)
+ return rec_res, time.time() - st
+
+
+def main(args):
+ image_file_list = get_image_file_list(args.image_dir)
+ text_recognizer = TextRecognizer(args)
+ valid_image_file_list = []
+ img_list = []
+
+ logger.info(
+ "In PP-OCRv3, rec_image_shape parameter defaults to '3, 48, 320', "
+ "if you are using recognition model with PP-OCRv2 or an older version, please set --rec_image_shape='3,32,320"
+ )
+ # warmup 2 times
+ if args.warmup:
+ img = np.random.uniform(0, 255, [48, 320, 3]).astype(np.uint8)
+ for i in range(2):
+ res = text_recognizer([img] * int(args.rec_batch_num))
+
+ for image_file in image_file_list:
+ img, flag, _ = check_and_read(image_file)
+ if not flag:
+ img = cv2.imread(image_file)
+ if img is None:
+ logger.info("error in loading image:{}".format(image_file))
+ continue
+ valid_image_file_list.append(image_file)
+ img_list.append(img)
+ try:
+ rec_res, _ = text_recognizer(img_list)
+
+ except Exception as E:
+ logger.info(traceback.format_exc())
+ logger.info(E)
+ exit()
+ for ino in range(len(img_list)):
+ logger.info("Predicts of {}:{}".format(valid_image_file_list[ino],
+ rec_res[ino]))
+ if args.benchmark:
+ text_recognizer.autolog.report()
+
+
+if __name__ == "__main__":
+ main(utility.parse_args())
diff --git a/ocr-studio/PaddleOCR/tools/infer/predict_sr.py b/ocr-studio/PaddleOCR/tools/infer/predict_sr.py
new file mode 100644
index 0000000000000000000000000000000000000000..ca99f6819f4b207ecc0f0d1383fe1d26d07fbf50
--- /dev/null
+++ b/ocr-studio/PaddleOCR/tools/infer/predict_sr.py
@@ -0,0 +1,155 @@
+# Copyright (c) 2020 PaddlePaddle Authors. All Rights Reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+import os
+import sys
+from PIL import Image
+__dir__ = os.path.dirname(os.path.abspath(__file__))
+sys.path.insert(0, __dir__)
+sys.path.insert(0, os.path.abspath(os.path.join(__dir__, '../..')))
+
+os.environ["FLAGS_allocator_strategy"] = 'auto_growth'
+
+import cv2
+import numpy as np
+import math
+import time
+import traceback
+import paddle
+
+import tools.infer.utility as utility
+from ppocr.postprocess import build_post_process
+from ppocr.utils.logging import get_logger
+from ppocr.utils.utility import get_image_file_list, check_and_read
+
+logger = get_logger()
+
+
+class TextSR(object):
+ def __init__(self, args):
+ self.sr_image_shape = [int(v) for v in args.sr_image_shape.split(",")]
+ self.sr_batch_num = args.sr_batch_num
+
+ self.predictor, self.input_tensor, self.output_tensors, self.config = \
+ utility.create_predictor(args, 'sr', logger)
+ self.benchmark = args.benchmark
+ if args.benchmark:
+ import auto_log
+ pid = os.getpid()
+ gpu_id = utility.get_infer_gpuid()
+ self.autolog = auto_log.AutoLogger(
+ model_name="sr",
+ model_precision=args.precision,
+ batch_size=args.sr_batch_num,
+ data_shape="dynamic",
+ save_path=None, #args.save_log_path,
+ inference_config=self.config,
+ pids=pid,
+ process_name=None,
+ gpu_ids=gpu_id if args.use_gpu else None,
+ time_keys=[
+ 'preprocess_time', 'inference_time', 'postprocess_time'
+ ],
+ warmup=0,
+ logger=logger)
+
+ def resize_norm_img(self, img):
+ imgC, imgH, imgW = self.sr_image_shape
+ img = img.resize((imgW // 2, imgH // 2), Image.BICUBIC)
+ img_numpy = np.array(img).astype("float32")
+ img_numpy = img_numpy.transpose((2, 0, 1)) / 255
+ return img_numpy
+
+ def __call__(self, img_list):
+ img_num = len(img_list)
+ batch_num = self.sr_batch_num
+ st = time.time()
+ st = time.time()
+ all_result = [] * img_num
+ if self.benchmark:
+ self.autolog.times.start()
+ for beg_img_no in range(0, img_num, batch_num):
+ end_img_no = min(img_num, beg_img_no + batch_num)
+ norm_img_batch = []
+ imgC, imgH, imgW = self.sr_image_shape
+ for ino in range(beg_img_no, end_img_no):
+ norm_img = self.resize_norm_img(img_list[ino])
+ norm_img = norm_img[np.newaxis, :]
+ norm_img_batch.append(norm_img)
+
+ norm_img_batch = np.concatenate(norm_img_batch)
+ norm_img_batch = norm_img_batch.copy()
+ if self.benchmark:
+ self.autolog.times.stamp()
+ self.input_tensor.copy_from_cpu(norm_img_batch)
+ self.predictor.run()
+ outputs = []
+ for output_tensor in self.output_tensors:
+ output = output_tensor.copy_to_cpu()
+ outputs.append(output)
+ if len(outputs) != 1:
+ preds = outputs
+ else:
+ preds = outputs[0]
+ all_result.append(outputs)
+ if self.benchmark:
+ self.autolog.times.end(stamp=True)
+ return all_result, time.time() - st
+
+
+def main(args):
+ image_file_list = get_image_file_list(args.image_dir)
+ text_recognizer = TextSR(args)
+ valid_image_file_list = []
+ img_list = []
+
+ # warmup 2 times
+ if args.warmup:
+ img = np.random.uniform(0, 255, [16, 64, 3]).astype(np.uint8)
+ for i in range(2):
+ res = text_recognizer([img] * int(args.sr_batch_num))
+
+ for image_file in image_file_list:
+ img, flag, _ = check_and_read(image_file)
+ if not flag:
+ img = Image.open(image_file).convert("RGB")
+ if img is None:
+ logger.info("error in loading image:{}".format(image_file))
+ continue
+ valid_image_file_list.append(image_file)
+ img_list.append(img)
+ try:
+ preds, _ = text_recognizer(img_list)
+ for beg_no in range(len(preds)):
+ sr_img = preds[beg_no][1]
+ lr_img = preds[beg_no][0]
+ for i in (range(sr_img.shape[0])):
+ fm_sr = (sr_img[i] * 255).transpose(1, 2, 0).astype(np.uint8)
+ fm_lr = (lr_img[i] * 255).transpose(1, 2, 0).astype(np.uint8)
+ img_name_pure = os.path.split(valid_image_file_list[
+ beg_no * args.sr_batch_num + i])[-1]
+ cv2.imwrite("infer_result/sr_{}".format(img_name_pure),
+ fm_sr[:, :, ::-1])
+ logger.info("The visualized image saved in infer_result/sr_{}".
+ format(img_name_pure))
+
+ except Exception as E:
+ logger.info(traceback.format_exc())
+ logger.info(E)
+ exit()
+ if args.benchmark:
+ text_recognizer.autolog.report()
+
+
+if __name__ == "__main__":
+ main(utility.parse_args())
diff --git a/ocr-studio/PaddleOCR/tools/infer/predict_system.py b/ocr-studio/PaddleOCR/tools/infer/predict_system.py
new file mode 100644
index 0000000000000000000000000000000000000000..8af45b4cf52eb6355c9d4e08bc609e6ea91dfb43
--- /dev/null
+++ b/ocr-studio/PaddleOCR/tools/infer/predict_system.py
@@ -0,0 +1,272 @@
+# Copyright (c) 2020 PaddlePaddle Authors. All Rights Reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+import os
+import sys
+import subprocess
+
+__dir__ = os.path.dirname(os.path.abspath(__file__))
+sys.path.append(__dir__)
+sys.path.insert(0, os.path.abspath(os.path.join(__dir__, '../..')))
+
+os.environ["FLAGS_allocator_strategy"] = 'auto_growth'
+
+import cv2
+import copy
+import numpy as np
+import json
+import time
+import logging
+from PIL import Image
+import tools.infer.utility as utility
+import tools.infer.predict_rec as predict_rec
+import tools.infer.predict_det as predict_det
+import tools.infer.predict_cls as predict_cls
+from ppocr.utils.utility import get_image_file_list, check_and_read
+from ppocr.utils.logging import get_logger
+from tools.infer.utility import draw_ocr_box_txt, get_rotate_crop_image, get_minarea_rect_crop
+logger = get_logger()
+
+
+class TextSystem(object):
+ def __init__(self, args):
+ if not args.show_log:
+ logger.setLevel(logging.INFO)
+
+ self.text_detector = predict_det.TextDetector(args)
+ self.text_recognizer = predict_rec.TextRecognizer(args)
+ self.use_angle_cls = args.use_angle_cls
+ self.drop_score = args.drop_score
+ if self.use_angle_cls:
+ self.text_classifier = predict_cls.TextClassifier(args)
+
+ self.args = args
+ self.crop_image_res_index = 0
+
+ def draw_crop_rec_res(self, output_dir, img_crop_list, rec_res):
+ os.makedirs(output_dir, exist_ok=True)
+ bbox_num = len(img_crop_list)
+ for bno in range(bbox_num):
+ cv2.imwrite(
+ os.path.join(output_dir,
+ f"mg_crop_{bno+self.crop_image_res_index}.jpg"),
+ img_crop_list[bno])
+ logger.debug(f"{bno}, {rec_res[bno]}")
+ self.crop_image_res_index += bbox_num
+
+ def __call__(self, img, cls=True):
+ time_dict = {'det': 0, 'rec': 0, 'cls': 0, 'all': 0}
+
+ if img is None:
+ logger.debug("no valid image provided")
+ return None, None, time_dict
+
+ start = time.time()
+ ori_im = img.copy()
+ dt_boxes, elapse = self.text_detector(img)
+ time_dict['det'] = elapse
+
+ if dt_boxes is None:
+ logger.debug("no dt_boxes found, elapsed : {}".format(elapse))
+ end = time.time()
+ time_dict['all'] = end - start
+ return None, None, time_dict
+ else:
+ logger.debug("dt_boxes num : {}, elapsed : {}".format(
+ len(dt_boxes), elapse))
+ img_crop_list = []
+
+ dt_boxes = sorted_boxes(dt_boxes)
+
+ for bno in range(len(dt_boxes)):
+ tmp_box = copy.deepcopy(dt_boxes[bno])
+ if self.args.det_box_type == "quad":
+ img_crop = get_rotate_crop_image(ori_im, tmp_box)
+ else:
+ img_crop = get_minarea_rect_crop(ori_im, tmp_box)
+ img_crop_list.append(img_crop)
+ if self.use_angle_cls and cls:
+ img_crop_list, angle_list, elapse = self.text_classifier(
+ img_crop_list)
+ time_dict['cls'] = elapse
+ logger.debug("cls num : {}, elapsed : {}".format(
+ len(img_crop_list), elapse))
+
+ rec_res, elapse = self.text_recognizer(img_crop_list)
+ time_dict['rec'] = elapse
+ logger.debug("rec_res num : {}, elapsed : {}".format(
+ len(rec_res), elapse))
+ if self.args.save_crop_res:
+ self.draw_crop_rec_res(self.args.crop_res_save_dir, img_crop_list,
+ rec_res)
+ filter_boxes, filter_rec_res = [], []
+ for box, rec_result in zip(dt_boxes, rec_res):
+ text, score = rec_result[0], rec_result[1]
+ if score >= self.drop_score:
+ filter_boxes.append(box)
+ filter_rec_res.append(rec_result)
+ end = time.time()
+ time_dict['all'] = end - start
+ return filter_boxes, filter_rec_res, time_dict
+
+
+def sorted_boxes(dt_boxes):
+ """
+ Sort text boxes in order from top to bottom, left to right
+ args:
+ dt_boxes(array):detected text boxes with shape [4, 2]
+ return:
+ sorted boxes(array) with shape [4, 2]
+ """
+ num_boxes = dt_boxes.shape[0]
+ sorted_boxes = sorted(dt_boxes, key=lambda x: (x[0][1], x[0][0]))
+ _boxes = list(sorted_boxes)
+
+ for i in range(num_boxes - 1):
+ for j in range(i, -1, -1):
+ if abs(_boxes[j + 1][0][1] - _boxes[j][0][1]) < 10 and \
+ (_boxes[j + 1][0][0] < _boxes[j][0][0]):
+ tmp = _boxes[j]
+ _boxes[j] = _boxes[j + 1]
+ _boxes[j + 1] = tmp
+ else:
+ break
+ return _boxes
+
+
+def main(args):
+ image_file_list = get_image_file_list(args.image_dir)
+ image_file_list = image_file_list[args.process_id::args.total_process_num]
+ text_sys = TextSystem(args)
+ is_visualize = True
+ font_path = args.vis_font_path
+ drop_score = args.drop_score
+ draw_img_save_dir = args.draw_img_save_dir
+ os.makedirs(draw_img_save_dir, exist_ok=True)
+ save_results = []
+
+ logger.info(
+ "In PP-OCRv3, rec_image_shape parameter defaults to '3, 48, 320', "
+ "if you are using recognition model with PP-OCRv2 or an older version, please set --rec_image_shape='3,32,320"
+ )
+
+ # warm up 10 times
+ if args.warmup:
+ img = np.random.uniform(0, 255, [640, 640, 3]).astype(np.uint8)
+ for i in range(10):
+ res = text_sys(img)
+
+ total_time = 0
+ cpu_mem, gpu_mem, gpu_util = 0, 0, 0
+ _st = time.time()
+ count = 0
+ for idx, image_file in enumerate(image_file_list):
+
+ img, flag_gif, flag_pdf = check_and_read(image_file)
+ if not flag_gif and not flag_pdf:
+ img = cv2.imread(image_file)
+ if not flag_pdf:
+ if img is None:
+ logger.debug("error in loading image:{}".format(image_file))
+ continue
+ imgs = [img]
+ else:
+ page_num = args.page_num
+ if page_num > len(img) or page_num == 0:
+ page_num = len(img)
+ imgs = img[:page_num]
+ for index, img in enumerate(imgs):
+ starttime = time.time()
+ dt_boxes, rec_res, time_dict = text_sys(img)
+ elapse = time.time() - starttime
+ total_time += elapse
+ if len(imgs) > 1:
+ logger.debug(
+ str(idx) + '_' + str(index) + " Predict time of %s: %.3fs"
+ % (image_file, elapse))
+ else:
+ logger.debug(
+ str(idx) + " Predict time of %s: %.3fs" % (image_file,
+ elapse))
+ for text, score in rec_res:
+ logger.debug("{}, {:.3f}".format(text, score))
+
+ res = [{
+ "transcription": rec_res[i][0],
+ "points": np.array(dt_boxes[i]).astype(np.int32).tolist(),
+ } for i in range(len(dt_boxes))]
+ if len(imgs) > 1:
+ save_pred = os.path.basename(image_file) + '_' + str(
+ index) + "\t" + json.dumps(
+ res, ensure_ascii=False) + "\n"
+ else:
+ save_pred = os.path.basename(image_file) + "\t" + json.dumps(
+ res, ensure_ascii=False) + "\n"
+ save_results.append(save_pred)
+
+ if is_visualize:
+ image = Image.fromarray(cv2.cvtColor(img, cv2.COLOR_BGR2RGB))
+ boxes = dt_boxes
+ txts = [rec_res[i][0] for i in range(len(rec_res))]
+ scores = [rec_res[i][1] for i in range(len(rec_res))]
+
+ draw_img = draw_ocr_box_txt(
+ image,
+ boxes,
+ txts,
+ scores,
+ drop_score=drop_score,
+ font_path=font_path)
+ if flag_gif:
+ save_file = image_file[:-3] + "png"
+ elif flag_pdf:
+ save_file = image_file.replace('.pdf',
+ '_' + str(index) + '.png')
+ else:
+ save_file = image_file
+ cv2.imwrite(
+ os.path.join(draw_img_save_dir,
+ os.path.basename(save_file)),
+ draw_img[:, :, ::-1])
+ logger.debug("The visualized image saved in {}".format(
+ os.path.join(draw_img_save_dir, os.path.basename(
+ save_file))))
+
+ logger.info("The predict total time is {}".format(time.time() - _st))
+ if args.benchmark:
+ text_sys.text_detector.autolog.report()
+ text_sys.text_recognizer.autolog.report()
+
+ with open(
+ os.path.join(draw_img_save_dir, "system_results.txt"),
+ 'w',
+ encoding='utf-8') as f:
+ f.writelines(save_results)
+
+
+if __name__ == "__main__":
+ args = utility.parse_args()
+ if args.use_mp:
+ p_list = []
+ total_process_num = args.total_process_num
+ for process_id in range(total_process_num):
+ cmd = [sys.executable, "-u"] + sys.argv + [
+ "--process_id={}".format(process_id),
+ "--use_mp={}".format(False)
+ ]
+ p = subprocess.Popen(cmd, stdout=sys.stdout, stderr=sys.stdout)
+ p_list.append(p)
+ for p in p_list:
+ p.wait()
+ else:
+ main(args)
diff --git a/ocr-studio/PaddleOCR/tools/infer/utility.py b/ocr-studio/PaddleOCR/tools/infer/utility.py
new file mode 100644
index 0000000000000000000000000000000000000000..6a3f9ff087bbf05c8761772ad81dd0c9cc9f8e75
--- /dev/null
+++ b/ocr-studio/PaddleOCR/tools/infer/utility.py
@@ -0,0 +1,684 @@
+# Copyright (c) 2020 PaddlePaddle Authors. All Rights Reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import argparse
+import os
+import sys
+import platform
+import cv2
+import numpy as np
+import paddle
+import PIL
+from PIL import Image, ImageDraw, ImageFont
+import math
+from paddle import inference
+import time
+import random
+from ppocr.utils.logging import get_logger
+
+
+def str2bool(v):
+ return v.lower() in ("true", "yes", "t", "y", "1")
+
+
+def str2int_tuple(v):
+ return tuple([int(i.strip()) for i in v.split(",")])
+
+
+def init_args():
+ parser = argparse.ArgumentParser()
+ # params for prediction engine
+ parser.add_argument("--use_gpu", type=str2bool, default=True)
+ parser.add_argument("--use_xpu", type=str2bool, default=False)
+ parser.add_argument("--use_npu", type=str2bool, default=False)
+ parser.add_argument("--use_mlu", type=str2bool, default=False)
+ parser.add_argument("--ir_optim", type=str2bool, default=True)
+ parser.add_argument("--use_tensorrt", type=str2bool, default=False)
+ parser.add_argument("--min_subgraph_size", type=int, default=15)
+ parser.add_argument("--precision", type=str, default="fp32")
+ parser.add_argument("--gpu_mem", type=int, default=500)
+ parser.add_argument("--gpu_id", type=int, default=0)
+
+ # params for text detector
+ parser.add_argument("--image_dir", type=str)
+ parser.add_argument("--page_num", type=int, default=0)
+ parser.add_argument("--det_algorithm", type=str, default='DB')
+ parser.add_argument("--det_model_dir", type=str)
+ parser.add_argument("--det_limit_side_len", type=float, default=960)
+ parser.add_argument("--det_limit_type", type=str, default='max')
+ parser.add_argument("--det_box_type", type=str, default='quad')
+
+ # DB parmas
+ parser.add_argument("--det_db_thresh", type=float, default=0.3)
+ parser.add_argument("--det_db_box_thresh", type=float, default=0.6)
+ parser.add_argument("--det_db_unclip_ratio", type=float, default=1.5)
+ parser.add_argument("--max_batch_size", type=int, default=10)
+ parser.add_argument("--use_dilation", type=str2bool, default=False)
+ parser.add_argument("--det_db_score_mode", type=str, default="fast")
+
+ # EAST parmas
+ parser.add_argument("--det_east_score_thresh", type=float, default=0.8)
+ parser.add_argument("--det_east_cover_thresh", type=float, default=0.1)
+ parser.add_argument("--det_east_nms_thresh", type=float, default=0.2)
+
+ # SAST parmas
+ parser.add_argument("--det_sast_score_thresh", type=float, default=0.5)
+ parser.add_argument("--det_sast_nms_thresh", type=float, default=0.2)
+
+ # PSE parmas
+ parser.add_argument("--det_pse_thresh", type=float, default=0)
+ parser.add_argument("--det_pse_box_thresh", type=float, default=0.85)
+ parser.add_argument("--det_pse_min_area", type=float, default=16)
+ parser.add_argument("--det_pse_scale", type=int, default=1)
+
+ # FCE parmas
+ parser.add_argument("--scales", type=list, default=[8, 16, 32])
+ parser.add_argument("--alpha", type=float, default=1.0)
+ parser.add_argument("--beta", type=float, default=1.0)
+ parser.add_argument("--fourier_degree", type=int, default=5)
+
+ # params for text recognizer
+ parser.add_argument("--rec_algorithm", type=str, default='SVTR_LCNet')
+ parser.add_argument("--rec_model_dir", type=str)
+ parser.add_argument("--rec_image_inverse", type=str2bool, default=True)
+ parser.add_argument("--rec_image_shape", type=str, default="3, 48, 320")
+ parser.add_argument("--rec_batch_num", type=int, default=6)
+ parser.add_argument("--max_text_length", type=int, default=25)
+ parser.add_argument(
+ "--rec_char_dict_path",
+ type=str,
+ default="./ppocr/utils/ppocr_keys_v1.txt")
+ parser.add_argument("--use_space_char", type=str2bool, default=True)
+ parser.add_argument(
+ "--vis_font_path", type=str, default="./doc/fonts/simfang.ttf")
+ parser.add_argument("--drop_score", type=float, default=0.5)
+
+ # params for e2e
+ parser.add_argument("--e2e_algorithm", type=str, default='PGNet')
+ parser.add_argument("--e2e_model_dir", type=str)
+ parser.add_argument("--e2e_limit_side_len", type=float, default=768)
+ parser.add_argument("--e2e_limit_type", type=str, default='max')
+
+ # PGNet parmas
+ parser.add_argument("--e2e_pgnet_score_thresh", type=float, default=0.5)
+ parser.add_argument(
+ "--e2e_char_dict_path", type=str, default="./ppocr/utils/ic15_dict.txt")
+ parser.add_argument("--e2e_pgnet_valid_set", type=str, default='totaltext')
+ parser.add_argument("--e2e_pgnet_mode", type=str, default='fast')
+
+ # params for text classifier
+ parser.add_argument("--use_angle_cls", type=str2bool, default=False)
+ parser.add_argument("--cls_model_dir", type=str)
+ parser.add_argument("--cls_image_shape", type=str, default="3, 48, 192")
+ parser.add_argument("--label_list", type=list, default=['0', '180'])
+ parser.add_argument("--cls_batch_num", type=int, default=6)
+ parser.add_argument("--cls_thresh", type=float, default=0.9)
+
+ parser.add_argument("--enable_mkldnn", type=str2bool, default=False)
+ parser.add_argument("--cpu_threads", type=int, default=10)
+ parser.add_argument("--use_pdserving", type=str2bool, default=False)
+ parser.add_argument("--warmup", type=str2bool, default=False)
+
+ # SR parmas
+ parser.add_argument("--sr_model_dir", type=str)
+ parser.add_argument("--sr_image_shape", type=str, default="3, 32, 128")
+ parser.add_argument("--sr_batch_num", type=int, default=1)
+
+ #
+ parser.add_argument(
+ "--draw_img_save_dir", type=str, default="./inference_results")
+ parser.add_argument("--save_crop_res", type=str2bool, default=False)
+ parser.add_argument("--crop_res_save_dir", type=str, default="./output")
+
+ # multi-process
+ parser.add_argument("--use_mp", type=str2bool, default=False)
+ parser.add_argument("--total_process_num", type=int, default=1)
+ parser.add_argument("--process_id", type=int, default=0)
+
+ parser.add_argument("--benchmark", type=str2bool, default=False)
+ parser.add_argument("--save_log_path", type=str, default="./log_output/")
+
+ parser.add_argument("--show_log", type=str2bool, default=True)
+ parser.add_argument("--use_onnx", type=str2bool, default=False)
+
+ # extended function
+ parser.add_argument("--return_word_box", type=str2bool, default=False, help='Whether return the bbox of each word (split by space) or chinese character. Only used in ppstructure for layout recovery')
+
+ return parser
+
+
+def parse_args():
+ parser = init_args()
+ return parser.parse_args()
+
+
+def create_predictor(args, mode, logger):
+ if mode == "det":
+ model_dir = args.det_model_dir
+ elif mode == 'cls':
+ model_dir = args.cls_model_dir
+ elif mode == 'rec':
+ model_dir = args.rec_model_dir
+ elif mode == 'table':
+ model_dir = args.table_model_dir
+ elif mode == 'ser':
+ model_dir = args.ser_model_dir
+ elif mode == 're':
+ model_dir = args.re_model_dir
+ elif mode == "sr":
+ model_dir = args.sr_model_dir
+ elif mode == 'layout':
+ model_dir = args.layout_model_dir
+ else:
+ model_dir = args.e2e_model_dir
+
+ if model_dir is None:
+ logger.info("not find {} model file path {}".format(mode, model_dir))
+ sys.exit(0)
+ if args.use_onnx:
+ import onnxruntime as ort
+ model_file_path = model_dir
+ if not os.path.exists(model_file_path):
+ raise ValueError("not find model file path {}".format(
+ model_file_path))
+ if args.use_gpu:
+ sess = ort.InferenceSession(model_file_path, providers=['CUDAExecutionProvider'])
+ else:
+ sess = ort.InferenceSession(model_file_path)
+ return sess, sess.get_inputs()[0], None, None
+
+ else:
+ file_names = ['model', 'inference']
+ for file_name in file_names:
+ model_file_path = '{}/{}.pdmodel'.format(model_dir, file_name)
+ params_file_path = '{}/{}.pdiparams'.format(model_dir, file_name)
+ if os.path.exists(model_file_path) and os.path.exists(
+ params_file_path):
+ break
+ if not os.path.exists(model_file_path):
+ raise ValueError(
+ "not find model.pdmodel or inference.pdmodel in {}".format(
+ model_dir))
+ if not os.path.exists(params_file_path):
+ raise ValueError(
+ "not find model.pdiparams or inference.pdiparams in {}".format(
+ model_dir))
+
+ config = inference.Config(model_file_path, params_file_path)
+
+ if hasattr(args, 'precision'):
+ if args.precision == "fp16" and args.use_tensorrt:
+ precision = inference.PrecisionType.Half
+ elif args.precision == "int8":
+ precision = inference.PrecisionType.Int8
+ else:
+ precision = inference.PrecisionType.Float32
+ else:
+ precision = inference.PrecisionType.Float32
+
+ if args.use_gpu:
+ gpu_id = get_infer_gpuid()
+ if gpu_id is None:
+ logger.warning(
+ "GPU is not found in current device by nvidia-smi. Please check your device or ignore it if run on jetson."
+ )
+ config.enable_use_gpu(args.gpu_mem, args.gpu_id)
+ if args.use_tensorrt:
+ config.enable_tensorrt_engine(
+ workspace_size=1 << 30,
+ precision_mode=precision,
+ max_batch_size=args.max_batch_size,
+ min_subgraph_size=args.
+ min_subgraph_size, # skip the minmum trt subgraph
+ use_calib_mode=False)
+
+ # collect shape
+ trt_shape_f = os.path.join(model_dir,
+ f"{mode}_trt_dynamic_shape.txt")
+
+ if not os.path.exists(trt_shape_f):
+ config.collect_shape_range_info(trt_shape_f)
+ logger.info(
+ f"collect dynamic shape info into : {trt_shape_f}")
+ try:
+ config.enable_tuned_tensorrt_dynamic_shape(trt_shape_f,
+ True)
+ except Exception as E:
+ logger.info(E)
+ logger.info("Please keep your paddlepaddle-gpu >= 2.3.0!")
+
+ elif args.use_npu:
+ config.enable_custom_device("npu")
+ elif args.use_mlu:
+ config.enable_custom_device("mlu")
+ elif args.use_xpu:
+ config.enable_xpu(10 * 1024 * 1024)
+ else:
+ config.disable_gpu()
+ if args.enable_mkldnn:
+ # cache 10 different shapes for mkldnn to avoid memory leak
+ config.set_mkldnn_cache_capacity(10)
+ config.enable_mkldnn()
+ if args.precision == "fp16":
+ config.enable_mkldnn_bfloat16()
+ if hasattr(args, "cpu_threads"):
+ config.set_cpu_math_library_num_threads(args.cpu_threads)
+ else:
+ # default cpu threads as 10
+ config.set_cpu_math_library_num_threads(10)
+ # enable memory optim
+ config.enable_memory_optim()
+ config.disable_glog_info()
+ config.delete_pass("conv_transpose_eltwiseadd_bn_fuse_pass")
+ config.delete_pass("matmul_transpose_reshape_fuse_pass")
+ if mode == 're':
+ config.delete_pass("simplify_with_basic_ops_pass")
+ if mode == 'table':
+ config.delete_pass("fc_fuse_pass") # not supported for table
+ config.switch_use_feed_fetch_ops(False)
+ config.switch_ir_optim(args.ir_optim)
+
+ # create predictor
+ predictor = inference.create_predictor(config)
+ input_names = predictor.get_input_names()
+ if mode in ['ser', 're']:
+ input_tensor = []
+ for name in input_names:
+ input_tensor.append(predictor.get_input_handle(name))
+ else:
+ for name in input_names:
+ input_tensor = predictor.get_input_handle(name)
+ output_tensors = get_output_tensors(args, mode, predictor)
+ return predictor, input_tensor, output_tensors, config
+
+
+def get_output_tensors(args, mode, predictor):
+ output_names = predictor.get_output_names()
+ output_tensors = []
+ if mode == "rec" and args.rec_algorithm in [
+ "CRNN", "SVTR_LCNet", "SVTR_HGNet"
+ ]:
+ output_name = 'softmax_0.tmp_0'
+ if output_name in output_names:
+ return [predictor.get_output_handle(output_name)]
+ else:
+ for output_name in output_names:
+ output_tensor = predictor.get_output_handle(output_name)
+ output_tensors.append(output_tensor)
+ else:
+ for output_name in output_names:
+ output_tensor = predictor.get_output_handle(output_name)
+ output_tensors.append(output_tensor)
+ return output_tensors
+
+
+def get_infer_gpuid():
+ sysstr = platform.system()
+ if sysstr == "Windows":
+ return 0
+
+ if not paddle.device.is_compiled_with_rocm:
+ cmd = "env | grep CUDA_VISIBLE_DEVICES"
+ else:
+ cmd = "env | grep HIP_VISIBLE_DEVICES"
+ env_cuda = os.popen(cmd).readlines()
+ if len(env_cuda) == 0:
+ return 0
+ else:
+ gpu_id = env_cuda[0].strip().split("=")[1]
+ return int(gpu_id[0])
+
+
+def draw_e2e_res(dt_boxes, strs, img_path):
+ src_im = cv2.imread(img_path)
+ for box, str in zip(dt_boxes, strs):
+ box = box.astype(np.int32).reshape((-1, 1, 2))
+ cv2.polylines(src_im, [box], True, color=(255, 255, 0), thickness=2)
+ cv2.putText(
+ src_im,
+ str,
+ org=(int(box[0, 0, 0]), int(box[0, 0, 1])),
+ fontFace=cv2.FONT_HERSHEY_COMPLEX,
+ fontScale=0.7,
+ color=(0, 255, 0),
+ thickness=1)
+ return src_im
+
+
+def draw_text_det_res(dt_boxes, img):
+ for box in dt_boxes:
+ box = np.array(box).astype(np.int32).reshape(-1, 2)
+ cv2.polylines(img, [box], True, color=(255, 255, 0), thickness=2)
+ return img
+
+
+def resize_img(img, input_size=600):
+ """
+ resize img and limit the longest side of the image to input_size
+ """
+ img = np.array(img)
+ im_shape = img.shape
+ im_size_max = np.max(im_shape[0:2])
+ im_scale = float(input_size) / float(im_size_max)
+ img = cv2.resize(img, None, None, fx=im_scale, fy=im_scale)
+ return img
+
+
+def draw_ocr(image,
+ boxes,
+ txts=None,
+ scores=None,
+ drop_score=0.5,
+ font_path="./doc/fonts/simfang.ttf"):
+ """
+ Visualize the results of OCR detection and recognition
+ args:
+ image(Image|array): RGB image
+ boxes(list): boxes with shape(N, 4, 2)
+ txts(list): the texts
+ scores(list): txxs corresponding scores
+ drop_score(float): only scores greater than drop_threshold will be visualized
+ font_path: the path of font which is used to draw text
+ return(array):
+ the visualized img
+ """
+ if scores is None:
+ scores = [1] * len(boxes)
+ box_num = len(boxes)
+ for i in range(box_num):
+ if scores is not None and (scores[i] < drop_score or
+ math.isnan(scores[i])):
+ continue
+ box = np.reshape(np.array(boxes[i]), [-1, 1, 2]).astype(np.int64)
+ image = cv2.polylines(np.array(image), [box], True, (255, 0, 0), 2)
+ if txts is not None:
+ img = np.array(resize_img(image, input_size=600))
+ txt_img = text_visual(
+ txts,
+ scores,
+ img_h=img.shape[0],
+ img_w=600,
+ threshold=drop_score,
+ font_path=font_path)
+ img = np.concatenate([np.array(img), np.array(txt_img)], axis=1)
+ return img
+ return image
+
+
+def draw_ocr_box_txt(image,
+ boxes,
+ txts=None,
+ scores=None,
+ drop_score=0.5,
+ font_path="./doc/fonts/simfang.ttf"):
+ h, w = image.height, image.width
+ img_left = image.copy()
+ img_right = np.ones((h, w, 3), dtype=np.uint8) * 255
+ random.seed(0)
+
+ draw_left = ImageDraw.Draw(img_left)
+ if txts is None or len(txts) != len(boxes):
+ txts = [None] * len(boxes)
+ for idx, (box, txt) in enumerate(zip(boxes, txts)):
+ if scores is not None and scores[idx] < drop_score:
+ continue
+ color = (random.randint(0, 255), random.randint(0, 255),
+ random.randint(0, 255))
+ draw_left.polygon(box, fill=color)
+ img_right_text = draw_box_txt_fine((w, h), box, txt, font_path)
+ pts = np.array(box, np.int32).reshape((-1, 1, 2))
+ cv2.polylines(img_right_text, [pts], True, color, 1)
+ img_right = cv2.bitwise_and(img_right, img_right_text)
+ img_left = Image.blend(image, img_left, 0.5)
+ img_show = Image.new('RGB', (w * 2, h), (255, 255, 255))
+ img_show.paste(img_left, (0, 0, w, h))
+ img_show.paste(Image.fromarray(img_right), (w, 0, w * 2, h))
+ return np.array(img_show)
+
+
+def draw_box_txt_fine(img_size, box, txt, font_path="./doc/fonts/simfang.ttf"):
+ box_height = int(
+ math.sqrt((box[0][0] - box[3][0])**2 + (box[0][1] - box[3][1])**2))
+ box_width = int(
+ math.sqrt((box[0][0] - box[1][0])**2 + (box[0][1] - box[1][1])**2))
+
+ if box_height > 2 * box_width and box_height > 30:
+ img_text = Image.new('RGB', (box_height, box_width), (255, 255, 255))
+ draw_text = ImageDraw.Draw(img_text)
+ if txt:
+ font = create_font(txt, (box_height, box_width), font_path)
+ draw_text.text([0, 0], txt, fill=(0, 0, 0), font=font)
+ img_text = img_text.transpose(Image.ROTATE_270)
+ else:
+ img_text = Image.new('RGB', (box_width, box_height), (255, 255, 255))
+ draw_text = ImageDraw.Draw(img_text)
+ if txt:
+ font = create_font(txt, (box_width, box_height), font_path)
+ draw_text.text([0, 0], txt, fill=(0, 0, 0), font=font)
+
+ pts1 = np.float32(
+ [[0, 0], [box_width, 0], [box_width, box_height], [0, box_height]])
+ pts2 = np.array(box, dtype=np.float32)
+ M = cv2.getPerspectiveTransform(pts1, pts2)
+
+ img_text = np.array(img_text, dtype=np.uint8)
+ img_right_text = cv2.warpPerspective(
+ img_text,
+ M,
+ img_size,
+ flags=cv2.INTER_NEAREST,
+ borderMode=cv2.BORDER_CONSTANT,
+ borderValue=(255, 255, 255))
+ return img_right_text
+
+
+def create_font(txt, sz, font_path="./doc/fonts/simfang.ttf"):
+ font_size = int(sz[1] * 0.99)
+ font = ImageFont.truetype(font_path, font_size, encoding="utf-8")
+ if int(PIL.__version__.split('.')[0]) < 10:
+ length = font.getsize(txt)[0]
+ else:
+ length = font.getlength(txt)
+
+ if length > sz[0]:
+ font_size = int(font_size * sz[0] / length)
+ font = ImageFont.truetype(font_path, font_size, encoding="utf-8")
+ return font
+
+
+def str_count(s):
+ """
+ Count the number of Chinese characters,
+ a single English character and a single number
+ equal to half the length of Chinese characters.
+ args:
+ s(string): the input of string
+ return(int):
+ the number of Chinese characters
+ """
+ import string
+ count_zh = count_pu = 0
+ s_len = len(s)
+ en_dg_count = 0
+ for c in s:
+ if c in string.ascii_letters or c.isdigit() or c.isspace():
+ en_dg_count += 1
+ elif c.isalpha():
+ count_zh += 1
+ else:
+ count_pu += 1
+ return s_len - math.ceil(en_dg_count / 2)
+
+
+def text_visual(texts,
+ scores,
+ img_h=400,
+ img_w=600,
+ threshold=0.,
+ font_path="./doc/simfang.ttf"):
+ """
+ create new blank img and draw txt on it
+ args:
+ texts(list): the text will be draw
+ scores(list|None): corresponding score of each txt
+ img_h(int): the height of blank img
+ img_w(int): the width of blank img
+ font_path: the path of font which is used to draw text
+ return(array):
+ """
+ if scores is not None:
+ assert len(texts) == len(
+ scores), "The number of txts and corresponding scores must match"
+
+ def create_blank_img():
+ blank_img = np.ones(shape=[img_h, img_w], dtype=np.int8) * 255
+ blank_img[:, img_w - 1:] = 0
+ blank_img = Image.fromarray(blank_img).convert("RGB")
+ draw_txt = ImageDraw.Draw(blank_img)
+ return blank_img, draw_txt
+
+ blank_img, draw_txt = create_blank_img()
+
+ font_size = 20
+ txt_color = (0, 0, 0)
+ font = ImageFont.truetype(font_path, font_size, encoding="utf-8")
+
+ gap = font_size + 5
+ txt_img_list = []
+ count, index = 1, 0
+ for idx, txt in enumerate(texts):
+ index += 1
+ if scores[idx] < threshold or math.isnan(scores[idx]):
+ index -= 1
+ continue
+ first_line = True
+ while str_count(txt) >= img_w // font_size - 4:
+ tmp = txt
+ txt = tmp[:img_w // font_size - 4]
+ if first_line:
+ new_txt = str(index) + ': ' + txt
+ first_line = False
+ else:
+ new_txt = ' ' + txt
+ draw_txt.text((0, gap * count), new_txt, txt_color, font=font)
+ txt = tmp[img_w // font_size - 4:]
+ if count >= img_h // gap - 1:
+ txt_img_list.append(np.array(blank_img))
+ blank_img, draw_txt = create_blank_img()
+ count = 0
+ count += 1
+ if first_line:
+ new_txt = str(index) + ': ' + txt + ' ' + '%.3f' % (scores[idx])
+ else:
+ new_txt = " " + txt + " " + '%.3f' % (scores[idx])
+ draw_txt.text((0, gap * count), new_txt, txt_color, font=font)
+ # whether add new blank img or not
+ if count >= img_h // gap - 1 and idx + 1 < len(texts):
+ txt_img_list.append(np.array(blank_img))
+ blank_img, draw_txt = create_blank_img()
+ count = 0
+ count += 1
+ txt_img_list.append(np.array(blank_img))
+ if len(txt_img_list) == 1:
+ blank_img = np.array(txt_img_list[0])
+ else:
+ blank_img = np.concatenate(txt_img_list, axis=1)
+ return np.array(blank_img)
+
+
+def base64_to_cv2(b64str):
+ import base64
+ data = base64.b64decode(b64str.encode('utf8'))
+ data = np.frombuffer(data, np.uint8)
+ data = cv2.imdecode(data, cv2.IMREAD_COLOR)
+ return data
+
+
+def draw_boxes(image, boxes, scores=None, drop_score=0.5):
+ if scores is None:
+ scores = [1] * len(boxes)
+ for (box, score) in zip(boxes, scores):
+ if score < drop_score:
+ continue
+ box = np.reshape(np.array(box), [-1, 1, 2]).astype(np.int64)
+ image = cv2.polylines(np.array(image), [box], True, (255, 0, 0), 2)
+ return image
+
+
+def get_rotate_crop_image(img, points):
+ '''
+ img_height, img_width = img.shape[0:2]
+ left = int(np.min(points[:, 0]))
+ right = int(np.max(points[:, 0]))
+ top = int(np.min(points[:, 1]))
+ bottom = int(np.max(points[:, 1]))
+ img_crop = img[top:bottom, left:right, :].copy()
+ points[:, 0] = points[:, 0] - left
+ points[:, 1] = points[:, 1] - top
+ '''
+ assert len(points) == 4, "shape of points must be 4*2"
+ img_crop_width = int(
+ max(
+ np.linalg.norm(points[0] - points[1]),
+ np.linalg.norm(points[2] - points[3])))
+ img_crop_height = int(
+ max(
+ np.linalg.norm(points[0] - points[3]),
+ np.linalg.norm(points[1] - points[2])))
+ pts_std = np.float32([[0, 0], [img_crop_width, 0],
+ [img_crop_width, img_crop_height],
+ [0, img_crop_height]])
+ M = cv2.getPerspectiveTransform(points, pts_std)
+ dst_img = cv2.warpPerspective(
+ img,
+ M, (img_crop_width, img_crop_height),
+ borderMode=cv2.BORDER_REPLICATE,
+ flags=cv2.INTER_CUBIC)
+ dst_img_height, dst_img_width = dst_img.shape[0:2]
+ if dst_img_height * 1.0 / dst_img_width >= 1.5:
+ dst_img = np.rot90(dst_img)
+ return dst_img
+
+
+def get_minarea_rect_crop(img, points):
+ bounding_box = cv2.minAreaRect(np.array(points).astype(np.int32))
+ points = sorted(list(cv2.boxPoints(bounding_box)), key=lambda x: x[0])
+
+ index_a, index_b, index_c, index_d = 0, 1, 2, 3
+ if points[1][1] > points[0][1]:
+ index_a = 0
+ index_d = 1
+ else:
+ index_a = 1
+ index_d = 0
+ if points[3][1] > points[2][1]:
+ index_b = 2
+ index_c = 3
+ else:
+ index_b = 3
+ index_c = 2
+
+ box = [points[index_a], points[index_b], points[index_c], points[index_d]]
+ crop_img = get_rotate_crop_image(img, np.array(box))
+ return crop_img
+
+
+def check_gpu(use_gpu):
+ if use_gpu and not paddle.is_compiled_with_cuda():
+ use_gpu = False
+ return use_gpu
+
+
+if __name__ == '__main__':
+ pass
diff --git a/ocr-studio/PaddleOCR/tools/infer_cls.py b/ocr-studio/PaddleOCR/tools/infer_cls.py
new file mode 100644
index 0000000000000000000000000000000000000000..7fd6b536fbe50fb1240d84ca3a5e87236940c0f5
--- /dev/null
+++ b/ocr-studio/PaddleOCR/tools/infer_cls.py
@@ -0,0 +1,85 @@
+# Copyright (c) 2020 PaddlePaddle Authors. All Rights Reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+from __future__ import absolute_import
+from __future__ import division
+from __future__ import print_function
+
+import numpy as np
+
+import os
+import sys
+
+__dir__ = os.path.dirname(os.path.abspath(__file__))
+sys.path.append(__dir__)
+sys.path.insert(0, os.path.abspath(os.path.join(__dir__, '..')))
+
+os.environ["FLAGS_allocator_strategy"] = 'auto_growth'
+
+import paddle
+
+from ppocr.data import create_operators, transform
+from ppocr.modeling.architectures import build_model
+from ppocr.postprocess import build_post_process
+from ppocr.utils.save_load import load_model
+from ppocr.utils.utility import get_image_file_list
+import tools.program as program
+
+
+def main():
+ global_config = config['Global']
+
+ # build post process
+ post_process_class = build_post_process(config['PostProcess'],
+ global_config)
+
+ # build model
+ model = build_model(config['Architecture'])
+
+ load_model(config, model)
+
+ # create data ops
+ transforms = []
+ for op in config['Eval']['dataset']['transforms']:
+ op_name = list(op)[0]
+ if 'Label' in op_name:
+ continue
+ elif op_name == 'KeepKeys':
+ op[op_name]['keep_keys'] = ['image']
+ elif op_name == "SSLRotateResize":
+ op[op_name]["mode"] = "test"
+ transforms.append(op)
+ global_config['infer_mode'] = True
+ ops = create_operators(transforms, global_config)
+
+ model.eval()
+ for file in get_image_file_list(config['Global']['infer_img']):
+ logger.info("infer_img: {}".format(file))
+ with open(file, 'rb') as f:
+ img = f.read()
+ data = {'image': img}
+ batch = transform(data, ops)
+
+ images = np.expand_dims(batch[0], axis=0)
+ images = paddle.to_tensor(images)
+ preds = model(images)
+ post_result = post_process_class(preds)
+ for rec_result in post_result:
+ logger.info('\t result: {}'.format(rec_result))
+ logger.info("success!")
+
+
+if __name__ == '__main__':
+ config, device, logger, vdl_writer = program.preprocess()
+ main()
diff --git a/ocr-studio/PaddleOCR/tools/infer_det.py b/ocr-studio/PaddleOCR/tools/infer_det.py
new file mode 100644
index 0000000000000000000000000000000000000000..097d032b99c7d25a3e9e3b1d781bbdbe4dde62fa
--- /dev/null
+++ b/ocr-studio/PaddleOCR/tools/infer_det.py
@@ -0,0 +1,133 @@
+# Copyright (c) 2020 PaddlePaddle Authors. All Rights Reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+from __future__ import absolute_import
+from __future__ import division
+from __future__ import print_function
+
+import numpy as np
+
+import os
+import sys
+
+__dir__ = os.path.dirname(os.path.abspath(__file__))
+sys.path.append(__dir__)
+sys.path.insert(0, os.path.abspath(os.path.join(__dir__, '..')))
+
+os.environ["FLAGS_allocator_strategy"] = 'auto_growth'
+
+import cv2
+import json
+import paddle
+
+from ppocr.data import create_operators, transform
+from ppocr.modeling.architectures import build_model
+from ppocr.postprocess import build_post_process
+from ppocr.utils.save_load import load_model
+from ppocr.utils.utility import get_image_file_list
+import tools.program as program
+
+
+def draw_det_res(dt_boxes, config, img, img_name, save_path):
+ import cv2
+ src_im = img
+ for box in dt_boxes:
+ box = np.array(box).astype(np.int32).reshape((-1, 1, 2))
+ cv2.polylines(src_im, [box], True, color=(255, 255, 0), thickness=2)
+ if not os.path.exists(save_path):
+ os.makedirs(save_path)
+ save_path = os.path.join(save_path, os.path.basename(img_name))
+ cv2.imwrite(save_path, src_im)
+ logger.info("The detected Image saved in {}".format(save_path))
+
+
+@paddle.no_grad()
+def main():
+ global_config = config['Global']
+
+ # build model
+ model = build_model(config['Architecture'])
+
+ load_model(config, model)
+ # build post process
+ post_process_class = build_post_process(config['PostProcess'])
+
+ # create data ops
+ transforms = []
+ for op in config['Eval']['dataset']['transforms']:
+ op_name = list(op)[0]
+ if 'Label' in op_name:
+ continue
+ elif op_name == 'KeepKeys':
+ op[op_name]['keep_keys'] = ['image', 'shape']
+ transforms.append(op)
+
+ ops = create_operators(transforms, global_config)
+
+ save_res_path = config['Global']['save_res_path']
+ if not os.path.exists(os.path.dirname(save_res_path)):
+ os.makedirs(os.path.dirname(save_res_path))
+
+ model.eval()
+ with open(save_res_path, "wb") as fout:
+ for file in get_image_file_list(config['Global']['infer_img']):
+ logger.info("infer_img: {}".format(file))
+ with open(file, 'rb') as f:
+ img = f.read()
+ data = {'image': img}
+ batch = transform(data, ops)
+
+ images = np.expand_dims(batch[0], axis=0)
+ shape_list = np.expand_dims(batch[1], axis=0)
+ images = paddle.to_tensor(images)
+ preds = model(images)
+ post_result = post_process_class(preds, shape_list)
+
+ src_img = cv2.imread(file)
+
+ dt_boxes_json = []
+ # parser boxes if post_result is dict
+ if isinstance(post_result, dict):
+ det_box_json = {}
+ for k in post_result.keys():
+ boxes = post_result[k][0]['points']
+ dt_boxes_list = []
+ for box in boxes:
+ tmp_json = {"transcription": ""}
+ tmp_json['points'] = np.array(box).tolist()
+ dt_boxes_list.append(tmp_json)
+ det_box_json[k] = dt_boxes_list
+ save_det_path = os.path.dirname(config['Global'][
+ 'save_res_path']) + "/det_results_{}/".format(k)
+ draw_det_res(boxes, config, src_img, file, save_det_path)
+ else:
+ boxes = post_result[0]['points']
+ dt_boxes_json = []
+ # write result
+ for box in boxes:
+ tmp_json = {"transcription": ""}
+ tmp_json['points'] = np.array(box).tolist()
+ dt_boxes_json.append(tmp_json)
+ save_det_path = os.path.dirname(config['Global'][
+ 'save_res_path']) + "/det_results/"
+ draw_det_res(boxes, config, src_img, file, save_det_path)
+ otstr = file + "\t" + json.dumps(dt_boxes_json) + "\n"
+ fout.write(otstr.encode())
+
+ logger.info("success!")
+
+
+if __name__ == '__main__':
+ config, device, logger, vdl_writer = program.preprocess()
+ main()
diff --git a/ocr-studio/PaddleOCR/tools/infer_e2e.py b/ocr-studio/PaddleOCR/tools/infer_e2e.py
new file mode 100644
index 0000000000000000000000000000000000000000..37fdcbaadc2984c9cf4fb105b7122db31b99be30
--- /dev/null
+++ b/ocr-studio/PaddleOCR/tools/infer_e2e.py
@@ -0,0 +1,174 @@
+# Copyright (c) 2020 PaddlePaddle Authors. All Rights Reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+from __future__ import absolute_import
+from __future__ import division
+from __future__ import print_function
+
+import numpy as np
+
+import os
+import sys
+
+__dir__ = os.path.dirname(os.path.abspath(__file__))
+sys.path.append(__dir__)
+sys.path.insert(0, os.path.abspath(os.path.join(__dir__, '..')))
+
+os.environ["FLAGS_allocator_strategy"] = 'auto_growth'
+
+import cv2
+import json
+import paddle
+
+from ppocr.data import create_operators, transform
+from ppocr.modeling.architectures import build_model
+from ppocr.postprocess import build_post_process
+from ppocr.utils.save_load import load_model
+from ppocr.utils.utility import get_image_file_list
+import tools.program as program
+from PIL import Image, ImageDraw, ImageFont
+import math
+
+
+def draw_e2e_res_for_chinese(image,
+ boxes,
+ txts,
+ config,
+ img_name,
+ font_path="./doc/simfang.ttf"):
+ h, w = image.height, image.width
+ img_left = image.copy()
+ img_right = Image.new('RGB', (w, h), (255, 255, 255))
+
+ import random
+
+ random.seed(0)
+ draw_left = ImageDraw.Draw(img_left)
+ draw_right = ImageDraw.Draw(img_right)
+ for idx, (box, txt) in enumerate(zip(boxes, txts)):
+ box = np.array(box)
+ box = [tuple(x) for x in box]
+ color = (random.randint(0, 255), random.randint(0, 255),
+ random.randint(0, 255))
+ draw_left.polygon(box, fill=color)
+ draw_right.polygon(box, outline=color)
+ font = ImageFont.truetype(font_path, 15, encoding="utf-8")
+ draw_right.text([box[0][0], box[0][1]], txt, fill=(0, 0, 0), font=font)
+ img_left = Image.blend(image, img_left, 0.5)
+ img_show = Image.new('RGB', (w * 2, h), (255, 255, 255))
+ img_show.paste(img_left, (0, 0, w, h))
+ img_show.paste(img_right, (w, 0, w * 2, h))
+
+ save_e2e_path = os.path.dirname(config['Global'][
+ 'save_res_path']) + "/e2e_results/"
+ if not os.path.exists(save_e2e_path):
+ os.makedirs(save_e2e_path)
+ save_path = os.path.join(save_e2e_path, os.path.basename(img_name))
+ cv2.imwrite(save_path, np.array(img_show)[:, :, ::-1])
+ logger.info("The e2e Image saved in {}".format(save_path))
+
+
+def draw_e2e_res(dt_boxes, strs, config, img, img_name):
+ if len(dt_boxes) > 0:
+ src_im = img
+ for box, str in zip(dt_boxes, strs):
+ box = box.astype(np.int32).reshape((-1, 1, 2))
+ cv2.polylines(src_im, [box], True, color=(255, 255, 0), thickness=2)
+ cv2.putText(
+ src_im,
+ str,
+ org=(int(box[0, 0, 0]), int(box[0, 0, 1])),
+ fontFace=cv2.FONT_HERSHEY_COMPLEX,
+ fontScale=0.7,
+ color=(0, 255, 0),
+ thickness=1)
+ save_det_path = os.path.dirname(config['Global'][
+ 'save_res_path']) + "/e2e_results/"
+ if not os.path.exists(save_det_path):
+ os.makedirs(save_det_path)
+ save_path = os.path.join(save_det_path, os.path.basename(img_name))
+ cv2.imwrite(save_path, src_im)
+ logger.info("The e2e Image saved in {}".format(save_path))
+
+
+def main():
+ global_config = config['Global']
+
+ # build model
+ model = build_model(config['Architecture'])
+
+ load_model(config, model)
+
+ # build post process
+ post_process_class = build_post_process(config['PostProcess'],
+ global_config)
+
+ # create data ops
+ transforms = []
+ for op in config['Eval']['dataset']['transforms']:
+ op_name = list(op)[0]
+ if 'Label' in op_name:
+ continue
+ elif op_name == 'KeepKeys':
+ op[op_name]['keep_keys'] = ['image', 'shape']
+ transforms.append(op)
+
+ ops = create_operators(transforms, global_config)
+
+ save_res_path = config['Global']['save_res_path']
+ if not os.path.exists(os.path.dirname(save_res_path)):
+ os.makedirs(os.path.dirname(save_res_path))
+
+ model.eval()
+ with open(save_res_path, "wb") as fout:
+ for file in get_image_file_list(config['Global']['infer_img']):
+ logger.info("infer_img: {}".format(file))
+ with open(file, 'rb') as f:
+ img = f.read()
+ data = {'image': img}
+ batch = transform(data, ops)
+ images = np.expand_dims(batch[0], axis=0)
+ shape_list = np.expand_dims(batch[1], axis=0)
+ images = paddle.to_tensor(images)
+ preds = model(images)
+ post_result = post_process_class(preds, shape_list)
+ points, strs = post_result['points'], post_result['texts']
+ # write result
+ dt_boxes_json = []
+ for poly, str in zip(points, strs):
+ tmp_json = {"transcription": str}
+ tmp_json['points'] = poly.tolist()
+ dt_boxes_json.append(tmp_json)
+ otstr = file + "\t" + json.dumps(dt_boxes_json) + "\n"
+ fout.write(otstr.encode())
+ src_img = cv2.imread(file)
+ if global_config['infer_visual_type'] == 'EN':
+ draw_e2e_res(points, strs, config, src_img, file)
+ elif global_config['infer_visual_type'] == 'CN':
+ src_img = Image.fromarray(
+ cv2.cvtColor(src_img, cv2.COLOR_BGR2RGB))
+ draw_e2e_res_for_chinese(
+ src_img,
+ points,
+ strs,
+ config,
+ file,
+ font_path="./doc/fonts/simfang.ttf")
+
+ logger.info("success!")
+
+
+if __name__ == '__main__':
+ config, device, logger, vdl_writer = program.preprocess()
+ main()
diff --git a/ocr-studio/PaddleOCR/tools/infer_kie.py b/ocr-studio/PaddleOCR/tools/infer_kie.py
new file mode 100644
index 0000000000000000000000000000000000000000..9375434cc887b08dfa746420a6c73c58c6e04797
--- /dev/null
+++ b/ocr-studio/PaddleOCR/tools/infer_kie.py
@@ -0,0 +1,176 @@
+# Copyright (c) 2020 PaddlePaddle Authors. All Rights Reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+from __future__ import absolute_import
+from __future__ import division
+from __future__ import print_function
+
+import numpy as np
+import paddle.nn.functional as F
+
+import os
+import sys
+
+__dir__ = os.path.dirname(os.path.abspath(__file__))
+sys.path.append(__dir__)
+sys.path.insert(0, os.path.abspath(os.path.join(__dir__, '..')))
+
+os.environ["FLAGS_allocator_strategy"] = 'auto_growth'
+
+import cv2
+import paddle
+
+from ppocr.data import create_operators, transform
+from ppocr.modeling.architectures import build_model
+from ppocr.utils.save_load import load_model
+import tools.program as program
+import time
+
+
+def read_class_list(filepath):
+ ret = {}
+ with open(filepath, "r") as f:
+ lines = f.readlines()
+ for idx, line in enumerate(lines):
+ ret[idx] = line.strip("\n")
+ return ret
+
+
+def draw_kie_result(batch, node, idx_to_cls, count):
+ img = batch[6].copy()
+ boxes = batch[7]
+ h, w = img.shape[:2]
+ pred_img = np.ones((h, w * 2, 3), dtype=np.uint8) * 255
+ max_value, max_idx = paddle.max(node, -1), paddle.argmax(node, -1)
+ node_pred_label = max_idx.numpy().tolist()
+ node_pred_score = max_value.numpy().tolist()
+
+ for i, box in enumerate(boxes):
+ if i >= len(node_pred_label):
+ break
+ new_box = [[box[0], box[1]], [box[2], box[1]], [box[2], box[3]],
+ [box[0], box[3]]]
+ Pts = np.array([new_box], np.int32)
+ cv2.polylines(
+ img, [Pts.reshape((-1, 1, 2))],
+ True,
+ color=(255, 255, 0),
+ thickness=1)
+ x_min = int(min([point[0] for point in new_box]))
+ y_min = int(min([point[1] for point in new_box]))
+
+ pred_label = node_pred_label[i]
+ if pred_label in idx_to_cls:
+ pred_label = idx_to_cls[pred_label]
+ pred_score = '{:.2f}'.format(node_pred_score[i])
+ text = pred_label + '(' + pred_score + ')'
+ cv2.putText(pred_img, text, (x_min * 2, y_min),
+ cv2.FONT_HERSHEY_SIMPLEX, 0.5, (255, 0, 0), 1)
+ vis_img = np.ones((h, w * 3, 3), dtype=np.uint8) * 255
+ vis_img[:, :w] = img
+ vis_img[:, w:] = pred_img
+ save_kie_path = os.path.dirname(config['Global'][
+ 'save_res_path']) + "/kie_results/"
+ if not os.path.exists(save_kie_path):
+ os.makedirs(save_kie_path)
+ save_path = os.path.join(save_kie_path, str(count) + ".png")
+ cv2.imwrite(save_path, vis_img)
+ logger.info("The Kie Image saved in {}".format(save_path))
+
+def write_kie_result(fout, node, data):
+ """
+ Write infer result to output file, sorted by the predict label of each line.
+ The format keeps the same as the input with additional score attribute.
+ """
+ import json
+ label = data['label']
+ annotations = json.loads(label)
+ max_value, max_idx = paddle.max(node, -1), paddle.argmax(node, -1)
+ node_pred_label = max_idx.numpy().tolist()
+ node_pred_score = max_value.numpy().tolist()
+ res = []
+ for i, label in enumerate(node_pred_label):
+ pred_score = '{:.2f}'.format(node_pred_score[i])
+ pred_res = {
+ 'label': label,
+ 'transcription': annotations[i]['transcription'],
+ 'score': pred_score,
+ 'points': annotations[i]['points'],
+ }
+ res.append(pred_res)
+ res.sort(key=lambda x: x['label'])
+ fout.writelines([json.dumps(res, ensure_ascii=False) + '\n'])
+
+def main():
+ global_config = config['Global']
+
+ # build model
+ model = build_model(config['Architecture'])
+ load_model(config, model)
+
+ # create data ops
+ transforms = []
+ for op in config['Eval']['dataset']['transforms']:
+ transforms.append(op)
+
+ data_dir = config['Eval']['dataset']['data_dir']
+
+ ops = create_operators(transforms, global_config)
+
+ save_res_path = config['Global']['save_res_path']
+ class_path = config['Global']['class_path']
+ idx_to_cls = read_class_list(class_path)
+ os.makedirs(os.path.dirname(save_res_path), exist_ok=True)
+
+ model.eval()
+
+ warmup_times = 0
+ count_t = []
+ with open(save_res_path, "w") as fout:
+ with open(config['Global']['infer_img'], "rb") as f:
+ lines = f.readlines()
+ for index, data_line in enumerate(lines):
+ if index == 10:
+ warmup_t = time.time()
+ data_line = data_line.decode('utf-8')
+ substr = data_line.strip("\n").split("\t")
+ img_path, label = data_dir + "/" + substr[0], substr[1]
+ data = {'img_path': img_path, 'label': label}
+ with open(data['img_path'], 'rb') as f:
+ img = f.read()
+ data['image'] = img
+ st = time.time()
+ batch = transform(data, ops)
+ batch_pred = [0] * len(batch)
+ for i in range(len(batch)):
+ batch_pred[i] = paddle.to_tensor(
+ np.expand_dims(
+ batch[i], axis=0))
+ st = time.time()
+ node, edge = model(batch_pred)
+ node = F.softmax(node, -1)
+ count_t.append(time.time() - st)
+ draw_kie_result(batch, node, idx_to_cls, index)
+ write_kie_result(fout, node, data)
+ fout.close()
+ logger.info("success!")
+ logger.info("It took {} s for predict {} images.".format(
+ np.sum(count_t), len(count_t)))
+ ips = len(count_t[warmup_times:]) / np.sum(count_t[warmup_times:])
+ logger.info("The ips is {} images/s".format(ips))
+
+
+if __name__ == '__main__':
+ config, device, logger, vdl_writer = program.preprocess()
+ main()
diff --git a/ocr-studio/PaddleOCR/tools/infer_kie_token_ser.py b/ocr-studio/PaddleOCR/tools/infer_kie_token_ser.py
new file mode 100644
index 0000000000000000000000000000000000000000..2fc5749b9c10b9c89bc16e561fbe9c5ce58eb13c
--- /dev/null
+++ b/ocr-studio/PaddleOCR/tools/infer_kie_token_ser.py
@@ -0,0 +1,157 @@
+# Copyright (c) 2020 PaddlePaddle Authors. All Rights Reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+from __future__ import absolute_import
+from __future__ import division
+from __future__ import print_function
+
+import numpy as np
+
+import os
+import sys
+
+__dir__ = os.path.dirname(os.path.abspath(__file__))
+sys.path.append(__dir__)
+sys.path.insert(0, os.path.abspath(os.path.join(__dir__, '..')))
+
+os.environ["FLAGS_allocator_strategy"] = 'auto_growth'
+import cv2
+import json
+import paddle
+
+from ppocr.data import create_operators, transform
+from ppocr.modeling.architectures import build_model
+from ppocr.postprocess import build_post_process
+from ppocr.utils.save_load import load_model
+from ppocr.utils.visual import draw_ser_results
+from ppocr.utils.utility import get_image_file_list, load_vqa_bio_label_maps
+import tools.program as program
+
+
+def to_tensor(data):
+ import numbers
+ from collections import defaultdict
+ data_dict = defaultdict(list)
+ to_tensor_idxs = []
+
+ for idx, v in enumerate(data):
+ if isinstance(v, (np.ndarray, paddle.Tensor, numbers.Number)):
+ if idx not in to_tensor_idxs:
+ to_tensor_idxs.append(idx)
+ data_dict[idx].append(v)
+ for idx in to_tensor_idxs:
+ data_dict[idx] = paddle.to_tensor(data_dict[idx])
+ return list(data_dict.values())
+
+
+class SerPredictor(object):
+ def __init__(self, config):
+ global_config = config['Global']
+ self.algorithm = config['Architecture']["algorithm"]
+
+ # build post process
+ self.post_process_class = build_post_process(config['PostProcess'],
+ global_config)
+
+ # build model
+ self.model = build_model(config['Architecture'])
+
+ load_model(
+ config, self.model, model_type=config['Architecture']["model_type"])
+
+ from paddleocr import PaddleOCR
+
+ self.ocr_engine = PaddleOCR(
+ use_angle_cls=False,
+ show_log=False,
+ rec_model_dir=global_config.get("kie_rec_model_dir", None),
+ det_model_dir=global_config.get("kie_det_model_dir", None),
+ use_gpu=global_config['use_gpu'])
+
+ # create data ops
+ transforms = []
+ for op in config['Eval']['dataset']['transforms']:
+ op_name = list(op)[0]
+ if 'Label' in op_name:
+ op[op_name]['ocr_engine'] = self.ocr_engine
+ elif op_name == 'KeepKeys':
+ op[op_name]['keep_keys'] = [
+ 'input_ids', 'bbox', 'attention_mask', 'token_type_ids',
+ 'image', 'labels', 'segment_offset_id', 'ocr_info',
+ 'entities'
+ ]
+
+ transforms.append(op)
+ if config["Global"].get("infer_mode", None) is None:
+ global_config['infer_mode'] = True
+ self.ops = create_operators(config['Eval']['dataset']['transforms'],
+ global_config)
+ self.model.eval()
+
+ def __call__(self, data):
+ with open(data["img_path"], 'rb') as f:
+ img = f.read()
+ data["image"] = img
+ batch = transform(data, self.ops)
+ batch = to_tensor(batch)
+ preds = self.model(batch)
+
+ post_result = self.post_process_class(
+ preds, segment_offset_ids=batch[6], ocr_infos=batch[7])
+ return post_result, batch
+
+
+if __name__ == '__main__':
+ config, device, logger, vdl_writer = program.preprocess()
+ os.makedirs(config['Global']['save_res_path'], exist_ok=True)
+
+ ser_engine = SerPredictor(config)
+
+ if config["Global"].get("infer_mode", None) is False:
+ data_dir = config['Eval']['dataset']['data_dir']
+ with open(config['Global']['infer_img'], "rb") as f:
+ infer_imgs = f.readlines()
+ else:
+ infer_imgs = get_image_file_list(config['Global']['infer_img'])
+
+ with open(
+ os.path.join(config['Global']['save_res_path'],
+ "infer_results.txt"),
+ "w",
+ encoding='utf-8') as fout:
+ for idx, info in enumerate(infer_imgs):
+ if config["Global"].get("infer_mode", None) is False:
+ data_line = info.decode('utf-8')
+ substr = data_line.strip("\n").split("\t")
+ img_path = os.path.join(data_dir, substr[0])
+ data = {'img_path': img_path, 'label': substr[1]}
+ else:
+ img_path = info
+ data = {'img_path': img_path}
+
+ save_img_path = os.path.join(
+ config['Global']['save_res_path'],
+ os.path.splitext(os.path.basename(img_path))[0] + "_ser.jpg")
+
+ result, _ = ser_engine(data)
+ result = result[0]
+ fout.write(img_path + "\t" + json.dumps(
+ {
+ "ocr_info": result,
+ }, ensure_ascii=False) + "\n")
+ img_res = draw_ser_results(img_path, result)
+ cv2.imwrite(save_img_path, img_res)
+
+ logger.info("process: [{}/{}], save result to {}".format(
+ idx, len(infer_imgs), save_img_path))
diff --git a/ocr-studio/PaddleOCR/tools/infer_kie_token_ser_re.py b/ocr-studio/PaddleOCR/tools/infer_kie_token_ser_re.py
new file mode 100644
index 0000000000000000000000000000000000000000..76120a913f36c815cbd3b9314523ea91e3290065
--- /dev/null
+++ b/ocr-studio/PaddleOCR/tools/infer_kie_token_ser_re.py
@@ -0,0 +1,225 @@
+# Copyright (c) 2020 PaddlePaddle Authors. All Rights Reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+from __future__ import absolute_import
+from __future__ import division
+from __future__ import print_function
+
+import numpy as np
+
+import os
+import sys
+
+__dir__ = os.path.dirname(os.path.abspath(__file__))
+sys.path.append(__dir__)
+sys.path.insert(0, os.path.abspath(os.path.join(__dir__, '..')))
+
+os.environ["FLAGS_allocator_strategy"] = 'auto_growth'
+import cv2
+import json
+import paddle
+import paddle.distributed as dist
+
+from ppocr.data import create_operators, transform
+from ppocr.modeling.architectures import build_model
+from ppocr.postprocess import build_post_process
+from ppocr.utils.save_load import load_model
+from ppocr.utils.visual import draw_re_results
+from ppocr.utils.logging import get_logger
+from ppocr.utils.utility import get_image_file_list, load_vqa_bio_label_maps, print_dict
+from tools.program import ArgsParser, load_config, merge_config
+from tools.infer_kie_token_ser import SerPredictor
+
+
+class ReArgsParser(ArgsParser):
+ def __init__(self):
+ super(ReArgsParser, self).__init__()
+ self.add_argument(
+ "-c_ser", "--config_ser", help="ser configuration file to use")
+ self.add_argument(
+ "-o_ser",
+ "--opt_ser",
+ nargs='+',
+ help="set ser configuration options ")
+
+ def parse_args(self, argv=None):
+ args = super(ReArgsParser, self).parse_args(argv)
+ assert args.config_ser is not None, \
+ "Please specify --config_ser=ser_configure_file_path."
+ args.opt_ser = self._parse_opt(args.opt_ser)
+ return args
+
+
+def make_input(ser_inputs, ser_results):
+ entities_labels = {'HEADER': 0, 'QUESTION': 1, 'ANSWER': 2}
+ batch_size, max_seq_len = ser_inputs[0].shape[:2]
+ entities = ser_inputs[8][0]
+ ser_results = ser_results[0]
+ assert len(entities) == len(ser_results)
+
+ # entities
+ start = []
+ end = []
+ label = []
+ entity_idx_dict = {}
+ for i, (res, entity) in enumerate(zip(ser_results, entities)):
+ if res['pred'] == 'O':
+ continue
+ entity_idx_dict[len(start)] = i
+ start.append(entity['start'])
+ end.append(entity['end'])
+ label.append(entities_labels[res['pred']])
+
+ entities = np.full([max_seq_len + 1, 3], fill_value=-1, dtype=np.int64)
+ entities[0, 0] = len(start)
+ entities[1:len(start) + 1, 0] = start
+ entities[0, 1] = len(end)
+ entities[1:len(end) + 1, 1] = end
+ entities[0, 2] = len(label)
+ entities[1:len(label) + 1, 2] = label
+
+ # relations
+ head = []
+ tail = []
+ for i in range(len(label)):
+ for j in range(len(label)):
+ if label[i] == 1 and label[j] == 2:
+ head.append(i)
+ tail.append(j)
+
+ relations = np.full([len(head) + 1, 2], fill_value=-1, dtype=np.int64)
+ relations[0, 0] = len(head)
+ relations[1:len(head) + 1, 0] = head
+ relations[0, 1] = len(tail)
+ relations[1:len(tail) + 1, 1] = tail
+
+ entities = np.expand_dims(entities, axis=0)
+ entities = np.repeat(entities, batch_size, axis=0)
+ relations = np.expand_dims(relations, axis=0)
+ relations = np.repeat(relations, batch_size, axis=0)
+
+ # remove ocr_info segment_offset_id and label in ser input
+ if isinstance(ser_inputs[0], paddle.Tensor):
+ entities = paddle.to_tensor(entities)
+ relations = paddle.to_tensor(relations)
+ ser_inputs = ser_inputs[:5] + [entities, relations]
+
+ entity_idx_dict_batch = []
+ for b in range(batch_size):
+ entity_idx_dict_batch.append(entity_idx_dict)
+ return ser_inputs, entity_idx_dict_batch
+
+
+class SerRePredictor(object):
+ def __init__(self, config, ser_config):
+ global_config = config['Global']
+ if "infer_mode" in global_config:
+ ser_config["Global"]["infer_mode"] = global_config["infer_mode"]
+
+ self.ser_engine = SerPredictor(ser_config)
+
+ # init re model
+
+ # build post process
+ self.post_process_class = build_post_process(config['PostProcess'],
+ global_config)
+
+ # build model
+ self.model = build_model(config['Architecture'])
+
+ load_model(
+ config, self.model, model_type=config['Architecture']["model_type"])
+
+ self.model.eval()
+
+ def __call__(self, data):
+ ser_results, ser_inputs = self.ser_engine(data)
+ re_input, entity_idx_dict_batch = make_input(ser_inputs, ser_results)
+ if self.model.backbone.use_visual_backbone is False:
+ re_input.pop(4)
+ preds = self.model(re_input)
+ post_result = self.post_process_class(
+ preds,
+ ser_results=ser_results,
+ entity_idx_dict_batch=entity_idx_dict_batch)
+ return post_result
+
+
+def preprocess():
+ FLAGS = ReArgsParser().parse_args()
+ config = load_config(FLAGS.config)
+ config = merge_config(config, FLAGS.opt)
+
+ ser_config = load_config(FLAGS.config_ser)
+ ser_config = merge_config(ser_config, FLAGS.opt_ser)
+
+ logger = get_logger()
+
+ # check if set use_gpu=True in paddlepaddle cpu version
+ use_gpu = config['Global']['use_gpu']
+
+ device = 'gpu:{}'.format(dist.ParallelEnv().dev_id) if use_gpu else 'cpu'
+ device = paddle.set_device(device)
+
+ logger.info('{} re config {}'.format('*' * 10, '*' * 10))
+ print_dict(config, logger)
+ logger.info('\n')
+ logger.info('{} ser config {}'.format('*' * 10, '*' * 10))
+ print_dict(ser_config, logger)
+ logger.info('train with paddle {} and device {}'.format(paddle.__version__,
+ device))
+ return config, ser_config, device, logger
+
+
+if __name__ == '__main__':
+ config, ser_config, device, logger = preprocess()
+ os.makedirs(config['Global']['save_res_path'], exist_ok=True)
+
+ ser_re_engine = SerRePredictor(config, ser_config)
+
+ if config["Global"].get("infer_mode", None) is False:
+ data_dir = config['Eval']['dataset']['data_dir']
+ with open(config['Global']['infer_img'], "rb") as f:
+ infer_imgs = f.readlines()
+ else:
+ infer_imgs = get_image_file_list(config['Global']['infer_img'])
+
+ with open(
+ os.path.join(config['Global']['save_res_path'],
+ "infer_results.txt"),
+ "w",
+ encoding='utf-8') as fout:
+ for idx, info in enumerate(infer_imgs):
+ if config["Global"].get("infer_mode", None) is False:
+ data_line = info.decode('utf-8')
+ substr = data_line.strip("\n").split("\t")
+ img_path = os.path.join(data_dir, substr[0])
+ data = {'img_path': img_path, 'label': substr[1]}
+ else:
+ img_path = info
+ data = {'img_path': img_path}
+
+ save_img_path = os.path.join(
+ config['Global']['save_res_path'],
+ os.path.splitext(os.path.basename(img_path))[0] + "_ser_re.jpg")
+
+ result = ser_re_engine(data)
+ result = result[0]
+ fout.write(img_path + "\t" + json.dumps(
+ result, ensure_ascii=False) + "\n")
+ img_res = draw_re_results(img_path, result)
+ cv2.imwrite(save_img_path, img_res)
+
+ logger.info("process: [{}/{}], save result to {}".format(
+ idx, len(infer_imgs), save_img_path))
diff --git a/ocr-studio/PaddleOCR/tools/infer_rec.py b/ocr-studio/PaddleOCR/tools/infer_rec.py
new file mode 100644
index 0000000000000000000000000000000000000000..8a7d59935664fc695403f3106bd2ab80637171cd
--- /dev/null
+++ b/ocr-studio/PaddleOCR/tools/infer_rec.py
@@ -0,0 +1,197 @@
+# Copyright (c) 2020 PaddlePaddle Authors. All Rights Reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+from __future__ import absolute_import
+from __future__ import division
+from __future__ import print_function
+
+import numpy as np
+
+import os
+import sys
+import json
+
+__dir__ = os.path.dirname(os.path.abspath(__file__))
+sys.path.append(__dir__)
+sys.path.insert(0, os.path.abspath(os.path.join(__dir__, '..')))
+
+os.environ["FLAGS_allocator_strategy"] = 'auto_growth'
+
+import paddle
+
+from ppocr.data import create_operators, transform
+from ppocr.modeling.architectures import build_model
+from ppocr.postprocess import build_post_process
+from ppocr.utils.save_load import load_model
+from ppocr.utils.utility import get_image_file_list
+import tools.program as program
+
+
+def main():
+ global_config = config['Global']
+
+ # build post process
+ post_process_class = build_post_process(config['PostProcess'],
+ global_config)
+
+ # build model
+ if hasattr(post_process_class, 'character'):
+ char_num = len(getattr(post_process_class, 'character'))
+ if config["Architecture"]["algorithm"] in ["Distillation",
+ ]: # distillation model
+ for key in config["Architecture"]["Models"]:
+ if config["Architecture"]["Models"][key]["Head"][
+ "name"] == 'MultiHead': # multi head
+ out_channels_list = {}
+ if config['PostProcess'][
+ 'name'] == 'DistillationSARLabelDecode':
+ char_num = char_num - 2
+ if config['PostProcess'][
+ 'name'] == 'DistillationNRTRLabelDecode':
+ char_num = char_num - 3
+ out_channels_list['CTCLabelDecode'] = char_num
+ out_channels_list['SARLabelDecode'] = char_num + 2
+ out_channels_list['NRTRLabelDecode'] = char_num + 3
+ config['Architecture']['Models'][key]['Head'][
+ 'out_channels_list'] = out_channels_list
+ else:
+ config["Architecture"]["Models"][key]["Head"][
+ "out_channels"] = char_num
+ elif config['Architecture']['Head'][
+ 'name'] == 'MultiHead': # multi head
+ out_channels_list = {}
+ char_num = len(getattr(post_process_class, 'character'))
+ if config['PostProcess']['name'] == 'SARLabelDecode':
+ char_num = char_num - 2
+ if config['PostProcess']['name'] == 'NRTRLabelDecode':
+ char_num = char_num - 3
+ out_channels_list['CTCLabelDecode'] = char_num
+ out_channels_list['SARLabelDecode'] = char_num + 2
+ out_channels_list['NRTRLabelDecode'] = char_num + 3
+ config['Architecture']['Head'][
+ 'out_channels_list'] = out_channels_list
+ else: # base rec model
+ config["Architecture"]["Head"]["out_channels"] = char_num
+ model = build_model(config['Architecture'])
+
+ load_model(config, model)
+
+ # create data ops
+ transforms = []
+ for op in config['Eval']['dataset']['transforms']:
+ op_name = list(op)[0]
+ if 'Label' in op_name:
+ continue
+ elif op_name in ['RecResizeImg']:
+ op[op_name]['infer_mode'] = True
+ elif op_name == 'KeepKeys':
+ if config['Architecture']['algorithm'] == "SRN":
+ op[op_name]['keep_keys'] = [
+ 'image', 'encoder_word_pos', 'gsrm_word_pos',
+ 'gsrm_slf_attn_bias1', 'gsrm_slf_attn_bias2'
+ ]
+ elif config['Architecture']['algorithm'] == "SAR":
+ op[op_name]['keep_keys'] = ['image', 'valid_ratio']
+ elif config['Architecture']['algorithm'] == "RobustScanner":
+ op[op_name][
+ 'keep_keys'] = ['image', 'valid_ratio', 'word_positons']
+ else:
+ op[op_name]['keep_keys'] = ['image']
+ transforms.append(op)
+ global_config['infer_mode'] = True
+ ops = create_operators(transforms, global_config)
+
+ save_res_path = config['Global'].get('save_res_path',
+ "./output/rec/predicts_rec.txt")
+ if not os.path.exists(os.path.dirname(save_res_path)):
+ os.makedirs(os.path.dirname(save_res_path))
+
+ model.eval()
+
+ infer_imgs = config['Global']['infer_img']
+ infer_list = config['Global'].get('infer_list', None)
+ with open(save_res_path, "w") as fout:
+ for file in get_image_file_list(infer_imgs, infer_list=infer_list):
+ logger.info("infer_img: {}".format(file))
+ with open(file, 'rb') as f:
+ img = f.read()
+ data = {'image': img}
+ batch = transform(data, ops)
+ if config['Architecture']['algorithm'] == "SRN":
+ encoder_word_pos_list = np.expand_dims(batch[1], axis=0)
+ gsrm_word_pos_list = np.expand_dims(batch[2], axis=0)
+ gsrm_slf_attn_bias1_list = np.expand_dims(batch[3], axis=0)
+ gsrm_slf_attn_bias2_list = np.expand_dims(batch[4], axis=0)
+
+ others = [
+ paddle.to_tensor(encoder_word_pos_list),
+ paddle.to_tensor(gsrm_word_pos_list),
+ paddle.to_tensor(gsrm_slf_attn_bias1_list),
+ paddle.to_tensor(gsrm_slf_attn_bias2_list)
+ ]
+ if config['Architecture']['algorithm'] == "SAR":
+ valid_ratio = np.expand_dims(batch[-1], axis=0)
+ img_metas = [paddle.to_tensor(valid_ratio)]
+ if config['Architecture']['algorithm'] == "RobustScanner":
+ valid_ratio = np.expand_dims(batch[1], axis=0)
+ word_positons = np.expand_dims(batch[2], axis=0)
+ img_metas = [
+ paddle.to_tensor(valid_ratio),
+ paddle.to_tensor(word_positons),
+ ]
+ if config['Architecture']['algorithm'] == "CAN":
+ image_mask = paddle.ones(
+ (np.expand_dims(
+ batch[0], axis=0).shape), dtype='float32')
+ label = paddle.ones((1, 36), dtype='int64')
+ images = np.expand_dims(batch[0], axis=0)
+ images = paddle.to_tensor(images)
+ if config['Architecture']['algorithm'] == "SRN":
+ preds = model(images, others)
+ elif config['Architecture']['algorithm'] == "SAR":
+ preds = model(images, img_metas)
+ elif config['Architecture']['algorithm'] == "RobustScanner":
+ preds = model(images, img_metas)
+ elif config['Architecture']['algorithm'] == "CAN":
+ preds = model([images, image_mask, label])
+ else:
+ preds = model(images)
+ post_result = post_process_class(preds)
+ info = None
+ if isinstance(post_result, dict):
+ rec_info = dict()
+ for key in post_result:
+ if len(post_result[key][0]) >= 2:
+ rec_info[key] = {
+ "label": post_result[key][0][0],
+ "score": float(post_result[key][0][1]),
+ }
+ info = json.dumps(rec_info, ensure_ascii=False)
+ elif isinstance(post_result, list) and isinstance(post_result[0],
+ int):
+ # for RFLearning CNT branch
+ info = str(post_result[0])
+ else:
+ if len(post_result[0]) >= 2:
+ info = post_result[0][0] + "\t" + str(post_result[0][1])
+
+ if info is not None:
+ logger.info("\t result: {}".format(info))
+ fout.write(file + "\t" + info + "\n")
+ logger.info("success!")
+
+
+if __name__ == '__main__':
+ config, device, logger, vdl_writer = program.preprocess()
+ main()
diff --git a/ocr-studio/PaddleOCR/tools/infer_sr.py b/ocr-studio/PaddleOCR/tools/infer_sr.py
new file mode 100644
index 0000000000000000000000000000000000000000..df4334f3427e57b9062dd819aa16c110fd771e8c
--- /dev/null
+++ b/ocr-studio/PaddleOCR/tools/infer_sr.py
@@ -0,0 +1,100 @@
+# Copyright (c) 2020 PaddlePaddle Authors. All Rights Reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+from __future__ import absolute_import
+from __future__ import division
+from __future__ import print_function
+
+import numpy as np
+
+import os
+import sys
+import json
+from PIL import Image
+import cv2
+
+__dir__ = os.path.dirname(os.path.abspath(__file__))
+sys.path.insert(0, __dir__)
+sys.path.insert(0, os.path.abspath(os.path.join(__dir__, '..')))
+
+os.environ["FLAGS_allocator_strategy"] = 'auto_growth'
+
+import paddle
+
+from ppocr.data import create_operators, transform
+from ppocr.modeling.architectures import build_model
+from ppocr.postprocess import build_post_process
+from ppocr.utils.save_load import load_model
+from ppocr.utils.utility import get_image_file_list
+import tools.program as program
+
+
+def main():
+ global_config = config['Global']
+
+ # build post process
+ post_process_class = build_post_process(config['PostProcess'],
+ global_config)
+
+ # sr transform
+ config['Architecture']["Transform"]['infer_mode'] = True
+
+ model = build_model(config['Architecture'])
+
+ load_model(config, model)
+
+ # create data ops
+ transforms = []
+ for op in config['Eval']['dataset']['transforms']:
+ op_name = list(op)[0]
+ if 'Label' in op_name:
+ continue
+ elif op_name in ['SRResize']:
+ op[op_name]['infer_mode'] = True
+ elif op_name == 'KeepKeys':
+ op[op_name]['keep_keys'] = ['img_lr']
+ transforms.append(op)
+ global_config['infer_mode'] = True
+ ops = create_operators(transforms, global_config)
+
+ save_visual_path = config['Global'].get('save_visual', "infer_result/")
+ if not os.path.exists(os.path.dirname(save_visual_path)):
+ os.makedirs(os.path.dirname(save_visual_path))
+
+ model.eval()
+ for file in get_image_file_list(config['Global']['infer_img']):
+ logger.info("infer_img: {}".format(file))
+ img = Image.open(file).convert("RGB")
+ data = {'image_lr': img}
+ batch = transform(data, ops)
+ images = np.expand_dims(batch[0], axis=0)
+ images = paddle.to_tensor(images)
+
+ preds = model(images)
+ sr_img = preds["sr_img"][0]
+ lr_img = preds["lr_img"][0]
+ fm_sr = (sr_img.numpy() * 255).transpose(1, 2, 0).astype(np.uint8)
+ fm_lr = (lr_img.numpy() * 255).transpose(1, 2, 0).astype(np.uint8)
+ img_name_pure = os.path.split(file)[-1]
+ cv2.imwrite("{}/sr_{}".format(save_visual_path, img_name_pure),
+ fm_sr[:, :, ::-1])
+ logger.info("The visualized image saved in infer_result/sr_{}".format(
+ img_name_pure))
+
+ logger.info("success!")
+
+
+if __name__ == '__main__':
+ config, device, logger, vdl_writer = program.preprocess()
+ main()
diff --git a/ocr-studio/PaddleOCR/tools/infer_table.py b/ocr-studio/PaddleOCR/tools/infer_table.py
new file mode 100644
index 0000000000000000000000000000000000000000..6dde5d67d061f4d0593928759db34bb9b22cde0d
--- /dev/null
+++ b/ocr-studio/PaddleOCR/tools/infer_table.py
@@ -0,0 +1,121 @@
+# Copyright (c) 2020 PaddlePaddle Authors. All Rights Reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+from __future__ import absolute_import
+from __future__ import division
+from __future__ import print_function
+
+import numpy as np
+
+import os
+import sys
+import json
+
+__dir__ = os.path.dirname(os.path.abspath(__file__))
+sys.path.append(__dir__)
+sys.path.insert(0, os.path.abspath(os.path.join(__dir__, '..')))
+
+os.environ["FLAGS_allocator_strategy"] = 'auto_growth'
+
+import paddle
+from paddle.jit import to_static
+
+from ppocr.data import create_operators, transform
+from ppocr.modeling.architectures import build_model
+from ppocr.postprocess import build_post_process
+from ppocr.utils.save_load import load_model
+from ppocr.utils.utility import get_image_file_list
+from ppocr.utils.visual import draw_rectangle
+from tools.infer.utility import draw_boxes
+import tools.program as program
+import cv2
+
+
+@paddle.no_grad()
+def main(config, device, logger, vdl_writer):
+ global_config = config['Global']
+
+ # build post process
+ post_process_class = build_post_process(config['PostProcess'],
+ global_config)
+
+ # build model
+ if hasattr(post_process_class, 'character'):
+ config['Architecture']["Head"]['out_channels'] = len(
+ getattr(post_process_class, 'character'))
+
+ model = build_model(config['Architecture'])
+ algorithm = config['Architecture']['algorithm']
+
+ load_model(config, model)
+
+ # create data ops
+ transforms = []
+ for op in config['Eval']['dataset']['transforms']:
+ op_name = list(op)[0]
+ if 'Encode' in op_name:
+ continue
+ if op_name == 'KeepKeys':
+ op[op_name]['keep_keys'] = ['image', 'shape']
+ transforms.append(op)
+
+ global_config['infer_mode'] = True
+ ops = create_operators(transforms, global_config)
+
+ save_res_path = config['Global']['save_res_path']
+ os.makedirs(save_res_path, exist_ok=True)
+
+ model.eval()
+ with open(
+ os.path.join(save_res_path, 'infer.txt'), mode='w',
+ encoding='utf-8') as f_w:
+ for file in get_image_file_list(config['Global']['infer_img']):
+ logger.info("infer_img: {}".format(file))
+ with open(file, 'rb') as f:
+ img = f.read()
+ data = {'image': img}
+ batch = transform(data, ops)
+ images = np.expand_dims(batch[0], axis=0)
+ shape_list = np.expand_dims(batch[1], axis=0)
+
+ images = paddle.to_tensor(images)
+ preds = model(images)
+ post_result = post_process_class(preds, [shape_list])
+
+ structure_str_list = post_result['structure_batch_list'][0]
+ bbox_list = post_result['bbox_batch_list'][0]
+ structure_str_list = structure_str_list[0]
+ structure_str_list = [
+ '', '', ''
+ ] + structure_str_list + ['
', '', '']
+ bbox_list_str = json.dumps(bbox_list.tolist())
+
+ logger.info("result: {}, {}".format(structure_str_list,
+ bbox_list_str))
+ f_w.write("result: {}, {}\n".format(structure_str_list,
+ bbox_list_str))
+
+ if len(bbox_list) > 0 and len(bbox_list[0]) == 4:
+ img = draw_rectangle(file, bbox_list)
+ else:
+ img = draw_boxes(cv2.imread(file), bbox_list)
+ cv2.imwrite(
+ os.path.join(save_res_path, os.path.basename(file)), img)
+ logger.info('save result to {}'.format(save_res_path))
+ logger.info("success!")
+
+
+if __name__ == '__main__':
+ config, device, logger, vdl_writer = program.preprocess()
+ main(config, device, logger, vdl_writer)
diff --git a/ocr-studio/PaddleOCR/tools/naive_sync_bn.py b/ocr-studio/PaddleOCR/tools/naive_sync_bn.py
new file mode 100644
index 0000000000000000000000000000000000000000..83df7c7b6ba62ef0a93cb406b693d21537f12a62
--- /dev/null
+++ b/ocr-studio/PaddleOCR/tools/naive_sync_bn.py
@@ -0,0 +1,120 @@
+# Copyright (c) 2024 PaddlePaddle Authors. All Rights Reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import paddle.distributed as dist
+import math
+import paddle
+import paddle.nn as nn
+
+
+class _AllReduce(paddle.autograd.PyLayer):
+ @staticmethod
+ def forward(ctx, input):
+ input_list = [paddle.zeros_like(input) for k in range(dist.get_world_size())]
+ # Use allgather instead of allreduce since I don't trust in-place operations ..
+ dist.all_gather(input_list, input, sync_op=True)
+ inputs = paddle.stack(input_list, axis=0)
+ return paddle.sum(inputs, axis=0)
+
+ @staticmethod
+ def backward(ctx, grad_output):
+ dist.all_reduce(grad_output, sync_op=True)
+ return grad_output
+
+
+def differentiable_all_reduce(input):
+ """
+ Differentiable counterpart of `dist.all_reduce`.
+ """
+ if (
+ not dist.is_available()
+ or not dist.is_initialized()
+ or dist.get_world_size() == 1
+ ):
+ return input
+ return _AllReduce.apply(input)
+
+
+class NaiveSyncBatchNorm(nn.BatchNorm2D):
+ def __init__(self, *args, stats_mode="", **kwargs):
+ super().__init__(*args, **kwargs)
+ assert stats_mode in ["", "N"]
+ self._stats_mode = stats_mode
+
+ def forward(self, input):
+ if dist.get_world_size() == 1 or not self.training:
+ return super().forward(input)
+
+ B, C = input.shape[0], input.shape[1]
+
+ mean = paddle.mean(input, axis=[0, 2, 3])
+ meansqr = paddle.mean(input * input, axis=[0, 2, 3])
+
+ if self._stats_mode == "":
+ assert (
+ B > 0
+ ), 'SyncBatchNorm(stats_mode="") does not support zero batch size.'
+ vec = paddle.concat([mean, meansqr], axis=0)
+ vec = differentiable_all_reduce(vec) * (1.0 / dist.get_world_size())
+ mean, meansqr = paddle.split(vec, [C, C])
+ momentum = (
+ 1 - self._momentum
+ ) # NOTE: paddle has reverse momentum definition
+ else:
+ if B == 0:
+ vec = paddle.zeros([2 * C + 1], dtype=mean.dtype)
+ vec = vec + input.sum() # make sure there is gradient w.r.t input
+ else:
+ vec = paddle.concat(
+ [
+ mean,
+ meansqr,
+ paddle.ones([1], dtype=mean.dtype),
+ ],
+ axis=0,
+ )
+ vec = differentiable_all_reduce(vec * B)
+
+ total_batch = vec[-1].detach()
+ momentum = total_batch.clip(max=1) * (
+ 1 - self._momentum
+ ) # no update if total_batch is 0
+ mean, meansqr, _ = paddle.split(
+ vec / total_batch.clip(min=1), [C, C, int(vec.shape[0] - 2 * C)]
+ ) # avoid div-by-zero
+
+ var = meansqr - mean * mean
+ invstd = paddle.rsqrt(var + self._epsilon)
+ scale = self.weight * invstd
+ bias = self.bias - mean * scale
+ scale = scale.reshape([1, -1, 1, 1])
+ bias = bias.reshape([1, -1, 1, 1])
+
+ tmp_mean = self._mean + momentum * (mean.detach() - self._mean)
+ self._mean.set_value(tmp_mean)
+ tmp_variance = self._variance + (momentum * (var.detach() - self._variance))
+ self._variance.set_value(tmp_variance)
+ ret = input * scale + bias
+ return ret
+
+
+def convert_syncbn(model):
+ for n, m in model.named_children():
+ if isinstance(m, nn.layer.norm._BatchNormBase):
+ syncbn = NaiveSyncBatchNorm(
+ m._num_features, m._momentum, m._epsilon, m._weight_attr, m._bias_attr
+ )
+ setattr(model, n, syncbn)
+ else:
+ convert_syncbn(m)
diff --git a/ocr-studio/PaddleOCR/tools/program.py b/ocr-studio/PaddleOCR/tools/program.py
new file mode 100644
index 0000000000000000000000000000000000000000..c543b7d85f7f484ace0131b0c8d1d1934b0073b8
--- /dev/null
+++ b/ocr-studio/PaddleOCR/tools/program.py
@@ -0,0 +1,717 @@
+# Copyright (c) 2021 PaddlePaddle Authors. All Rights Reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+from __future__ import absolute_import
+from __future__ import division
+from __future__ import print_function
+
+import os
+import sys
+import platform
+import yaml
+import time
+import datetime
+import paddle
+import paddle.distributed as dist
+from tqdm import tqdm
+import cv2
+import numpy as np
+from argparse import ArgumentParser, RawDescriptionHelpFormatter
+
+from ppocr.utils.stats import TrainingStats
+from ppocr.utils.save_load import save_model
+from ppocr.utils.utility import print_dict, AverageMeter
+from ppocr.utils.logging import get_logger
+from ppocr.utils.loggers import VDLLogger, WandbLogger, Loggers
+from ppocr.utils import profiler
+from ppocr.data import build_dataloader
+
+
+class ArgsParser(ArgumentParser):
+ def __init__(self):
+ super(ArgsParser, self).__init__(
+ formatter_class=RawDescriptionHelpFormatter)
+ self.add_argument("-c", "--config", help="configuration file to use")
+ self.add_argument(
+ "-o", "--opt", nargs='+', help="set configuration options")
+ self.add_argument(
+ '-p',
+ '--profiler_options',
+ type=str,
+ default=None,
+ help='The option of profiler, which should be in format ' \
+ '\"key1=value1;key2=value2;key3=value3\".'
+ )
+
+ def parse_args(self, argv=None):
+ args = super(ArgsParser, self).parse_args(argv)
+ assert args.config is not None, \
+ "Please specify --config=configure_file_path."
+ args.opt = self._parse_opt(args.opt)
+ return args
+
+ def _parse_opt(self, opts):
+ config = {}
+ if not opts:
+ return config
+ for s in opts:
+ s = s.strip()
+ k, v = s.split('=')
+ config[k] = yaml.load(v, Loader=yaml.Loader)
+ return config
+
+
+def load_config(file_path):
+ """
+ Load config from yml/yaml file.
+ Args:
+ file_path (str): Path of the config file to be loaded.
+ Returns: global config
+ """
+ _, ext = os.path.splitext(file_path)
+ assert ext in ['.yml', '.yaml'], "only support yaml files for now"
+ config = yaml.load(open(file_path, 'rb'), Loader=yaml.Loader)
+ return config
+
+
+def merge_config(config, opts):
+ """
+ Merge config into global config.
+ Args:
+ config (dict): Config to be merged.
+ Returns: global config
+ """
+ for key, value in opts.items():
+ if "." not in key:
+ if isinstance(value, dict) and key in config:
+ config[key].update(value)
+ else:
+ config[key] = value
+ else:
+ sub_keys = key.split('.')
+ assert (
+ sub_keys[0] in config
+ ), "the sub_keys can only be one of global_config: {}, but get: " \
+ "{}, please check your running command".format(
+ config.keys(), sub_keys[0])
+ cur = config[sub_keys[0]]
+ for idx, sub_key in enumerate(sub_keys[1:]):
+ if idx == len(sub_keys) - 2:
+ cur[sub_key] = value
+ else:
+ cur = cur[sub_key]
+ return config
+
+
+def check_device(use_gpu, use_xpu=False, use_npu=False, use_mlu=False):
+ """
+ Log error and exit when set use_gpu=true in paddlepaddle
+ cpu version.
+ """
+ err = "Config {} cannot be set as true while your paddle " \
+ "is not compiled with {} ! \nPlease try: \n" \
+ "\t1. Install paddlepaddle to run model on {} \n" \
+ "\t2. Set {} as false in config file to run " \
+ "model on CPU"
+
+ try:
+ if use_gpu and use_xpu:
+ print("use_xpu and use_gpu can not both be ture.")
+ if use_gpu and not paddle.is_compiled_with_cuda():
+ print(err.format("use_gpu", "cuda", "gpu", "use_gpu"))
+ sys.exit(1)
+ if use_xpu and not paddle.device.is_compiled_with_xpu():
+ print(err.format("use_xpu", "xpu", "xpu", "use_xpu"))
+ sys.exit(1)
+ if use_npu:
+ if int(paddle.version.major) != 0 and int(
+ paddle.version.major) <= 2 and int(
+ paddle.version.minor) <= 4:
+ if not paddle.device.is_compiled_with_npu():
+ print(err.format("use_npu", "npu", "npu", "use_npu"))
+ sys.exit(1)
+ # is_compiled_with_npu() has been updated after paddle-2.4
+ else:
+ if not paddle.device.is_compiled_with_custom_device("npu"):
+ print(err.format("use_npu", "npu", "npu", "use_npu"))
+ sys.exit(1)
+ if use_mlu and not paddle.device.is_compiled_with_mlu():
+ print(err.format("use_mlu", "mlu", "mlu", "use_mlu"))
+ sys.exit(1)
+ except Exception as e:
+ pass
+
+
+def to_float32(preds):
+ if isinstance(preds, dict):
+ for k in preds:
+ if isinstance(preds[k], dict) or isinstance(preds[k], list):
+ preds[k] = to_float32(preds[k])
+ elif isinstance(preds[k], paddle.Tensor):
+ preds[k] = preds[k].astype(paddle.float32)
+ elif isinstance(preds, list):
+ for k in range(len(preds)):
+ if isinstance(preds[k], dict):
+ preds[k] = to_float32(preds[k])
+ elif isinstance(preds[k], list):
+ preds[k] = to_float32(preds[k])
+ elif isinstance(preds[k], paddle.Tensor):
+ preds[k] = preds[k].astype(paddle.float32)
+ elif isinstance(preds, paddle.Tensor):
+ preds = preds.astype(paddle.float32)
+ return preds
+
+
+def train(config,
+ train_dataloader,
+ valid_dataloader,
+ device,
+ model,
+ loss_class,
+ optimizer,
+ lr_scheduler,
+ post_process_class,
+ eval_class,
+ pre_best_model_dict,
+ logger,
+ step_pre_epoch,
+ log_writer=None,
+ scaler=None,
+ amp_level='O2',
+ amp_custom_black_list=[],
+ amp_custom_white_list=[],
+ amp_dtype='float16'):
+ cal_metric_during_train = config['Global'].get('cal_metric_during_train',
+ False)
+ calc_epoch_interval = config['Global'].get('calc_epoch_interval', 1)
+ log_smooth_window = config['Global']['log_smooth_window']
+ epoch_num = config['Global']['epoch_num']
+ print_batch_step = config['Global']['print_batch_step']
+ eval_batch_step = config['Global']['eval_batch_step']
+ eval_batch_epoch = config['Global'].get('eval_batch_epoch', None)
+ profiler_options = config['profiler_options']
+
+ global_step = 0
+ if 'global_step' in pre_best_model_dict:
+ global_step = pre_best_model_dict['global_step']
+ start_eval_step = 0
+ if type(eval_batch_step) == list and len(eval_batch_step) >= 2:
+ start_eval_step = eval_batch_step[0] if not eval_batch_epoch else 0
+ eval_batch_step = eval_batch_step[
+ 1] if not eval_batch_epoch else step_pre_epoch * eval_batch_epoch
+ if len(valid_dataloader) == 0:
+ logger.info(
+ 'No Images in eval dataset, evaluation during training ' \
+ 'will be disabled'
+ )
+ start_eval_step = 1e111
+ logger.info(
+ "During the training process, after the {}th iteration, " \
+ "an evaluation is run every {} iterations".
+ format(start_eval_step, eval_batch_step))
+ save_epoch_step = config['Global']['save_epoch_step']
+ save_model_dir = config['Global']['save_model_dir']
+ if not os.path.exists(save_model_dir):
+ os.makedirs(save_model_dir)
+ main_indicator = eval_class.main_indicator
+ best_model_dict = {main_indicator: 0}
+ best_model_dict.update(pre_best_model_dict)
+ train_stats = TrainingStats(log_smooth_window, ['lr'])
+ model_average = False
+ model.train()
+
+ use_srn = config['Architecture']['algorithm'] == "SRN"
+ extra_input_models = [
+ "SRN", "NRTR", "SAR", "SEED", "SVTR", "SVTR_LCNet", "SPIN", "VisionLAN",
+ "RobustScanner", "RFL", 'DRRG', 'SATRN', 'SVTR_HGNet', "ParseQ", "CPPD"
+ ]
+ extra_input = False
+ if config['Architecture']['algorithm'] == 'Distillation':
+ for key in config['Architecture']["Models"]:
+ extra_input = extra_input or config['Architecture']['Models'][key][
+ 'algorithm'] in extra_input_models
+ else:
+ extra_input = config['Architecture']['algorithm'] in extra_input_models
+ try:
+ model_type = config['Architecture']['model_type']
+ except:
+ model_type = None
+
+ algorithm = config['Architecture']['algorithm']
+
+ start_epoch = best_model_dict[
+ 'start_epoch'] if 'start_epoch' in best_model_dict else 1
+
+ total_samples = 0
+ train_reader_cost = 0.0
+ train_batch_cost = 0.0
+ reader_start = time.time()
+ eta_meter = AverageMeter()
+
+ max_iter = len(train_dataloader) - 1 if platform.system(
+ ) == "Windows" else len(train_dataloader)
+
+ for epoch in range(start_epoch, epoch_num + 1):
+ if train_dataloader.dataset.need_reset:
+ train_dataloader = build_dataloader(
+ config, 'Train', device, logger, seed=epoch)
+ max_iter = len(train_dataloader) - 1 if platform.system(
+ ) == "Windows" else len(train_dataloader)
+
+ for idx, batch in enumerate(train_dataloader):
+ profiler.add_profiler_step(profiler_options)
+ train_reader_cost += time.time() - reader_start
+ if idx >= max_iter:
+ break
+ lr = optimizer.get_lr()
+ images = batch[0]
+ if use_srn:
+ model_average = True
+ # use amp
+ if scaler:
+ with paddle.amp.auto_cast(
+ level=amp_level,
+ custom_black_list=amp_custom_black_list,
+ custom_white_list=amp_custom_white_list,
+ dtype=amp_dtype):
+ if model_type == 'table' or extra_input:
+ preds = model(images, data=batch[1:])
+ elif model_type in ["kie"]:
+ preds = model(batch)
+ elif algorithm in ['CAN']:
+ preds = model(batch[:3])
+ else:
+ preds = model(images)
+ preds = to_float32(preds)
+ loss = loss_class(preds, batch)
+ avg_loss = loss['loss']
+ scaled_avg_loss = scaler.scale(avg_loss)
+ scaled_avg_loss.backward()
+ scaler.minimize(optimizer, scaled_avg_loss)
+ else:
+ if model_type == 'table' or extra_input:
+ preds = model(images, data=batch[1:])
+ elif model_type in ["kie", 'sr']:
+ preds = model(batch)
+ elif algorithm in ['CAN']:
+ preds = model(batch[:3])
+ else:
+ preds = model(images)
+ loss = loss_class(preds, batch)
+ avg_loss = loss['loss']
+ avg_loss.backward()
+ optimizer.step()
+
+ optimizer.clear_grad()
+
+ if cal_metric_during_train and epoch % calc_epoch_interval == 0: # only rec and cls need
+ batch = [item.numpy() for item in batch]
+ if model_type in ['kie', 'sr']:
+ eval_class(preds, batch)
+ elif model_type in ['table']:
+ post_result = post_process_class(preds, batch)
+ eval_class(post_result, batch)
+ elif algorithm in ['CAN']:
+ model_type = 'can'
+ eval_class(preds[0], batch[2:], epoch_reset=(idx == 0))
+ else:
+ if config['Loss']['name'] in ['MultiLoss', 'MultiLoss_v2'
+ ]: # for multi head loss
+ post_result = post_process_class(
+ preds['ctc'], batch[1]) # for CTC head out
+ elif config['Loss']['name'] in ['VLLoss']:
+ post_result = post_process_class(preds, batch[1],
+ batch[-1])
+ else:
+ post_result = post_process_class(preds, batch[1])
+ eval_class(post_result, batch)
+ metric = eval_class.get_metric()
+ train_stats.update(metric)
+
+ train_batch_time = time.time() - reader_start
+ train_batch_cost += train_batch_time
+ eta_meter.update(train_batch_time)
+ global_step += 1
+ total_samples += len(images)
+
+ if not isinstance(lr_scheduler, float):
+ lr_scheduler.step()
+
+ # logger and visualdl
+ stats = {
+ k: float(v) if v.shape == [] else v.numpy().mean()
+ for k, v in loss.items()
+ }
+ stats['lr'] = lr
+ train_stats.update(stats)
+
+ if log_writer is not None and dist.get_rank() == 0:
+ log_writer.log_metrics(
+ metrics=train_stats.get(), prefix="TRAIN", step=global_step)
+
+ if dist.get_rank() == 0 and (
+ (global_step > 0 and global_step % print_batch_step == 0) or
+ (idx >= len(train_dataloader) - 1)):
+ logs = train_stats.log()
+
+ eta_sec = ((epoch_num + 1 - epoch) * \
+ len(train_dataloader) - idx - 1) * eta_meter.avg
+ eta_sec_format = str(datetime.timedelta(seconds=int(eta_sec)))
+ strs = 'epoch: [{}/{}], global_step: {}, {}, avg_reader_cost: ' \
+ '{:.5f} s, avg_batch_cost: {:.5f} s, avg_samples: {}, ' \
+ 'ips: {:.5f} samples/s, eta: {}'.format(
+ epoch, epoch_num, global_step, logs,
+ train_reader_cost / print_batch_step,
+ train_batch_cost / print_batch_step,
+ total_samples / print_batch_step,
+ total_samples / train_batch_cost, eta_sec_format)
+ logger.info(strs)
+
+ total_samples = 0
+ train_reader_cost = 0.0
+ train_batch_cost = 0.0
+ # eval
+ if global_step > start_eval_step and \
+ (global_step - start_eval_step) % eval_batch_step == 0 \
+ and dist.get_rank() == 0:
+ if model_average:
+ Model_Average = paddle.incubate.optimizer.ModelAverage(
+ 0.15,
+ parameters=model.parameters(),
+ min_average_window=10000,
+ max_average_window=15625)
+ Model_Average.apply()
+ cur_metric = eval(
+ model,
+ valid_dataloader,
+ post_process_class,
+ eval_class,
+ model_type,
+ extra_input=extra_input,
+ scaler=scaler,
+ amp_level=amp_level,
+ amp_custom_black_list=amp_custom_black_list,
+ amp_custom_white_list=amp_custom_white_list,
+ amp_dtype=amp_dtype)
+ cur_metric_str = 'cur metric, {}'.format(', '.join(
+ ['{}: {}'.format(k, v) for k, v in cur_metric.items()]))
+ logger.info(cur_metric_str)
+
+ # logger metric
+ if log_writer is not None:
+ log_writer.log_metrics(
+ metrics=cur_metric, prefix="EVAL", step=global_step)
+
+ if cur_metric[main_indicator] >= best_model_dict[
+ main_indicator]:
+ best_model_dict.update(cur_metric)
+ best_model_dict['best_epoch'] = epoch
+ save_model(
+ model,
+ optimizer,
+ save_model_dir,
+ logger,
+ config,
+ is_best=True,
+ prefix='best_accuracy',
+ best_model_dict=best_model_dict,
+ epoch=epoch,
+ global_step=global_step)
+ best_str = 'best metric, {}'.format(', '.join([
+ '{}: {}'.format(k, v) for k, v in best_model_dict.items()
+ ]))
+ logger.info(best_str)
+ # logger best metric
+ if log_writer is not None:
+ log_writer.log_metrics(
+ metrics={
+ "best_{}".format(main_indicator):
+ best_model_dict[main_indicator]
+ },
+ prefix="EVAL",
+ step=global_step)
+
+ log_writer.log_model(
+ is_best=True,
+ prefix="best_accuracy",
+ metadata=best_model_dict)
+
+ reader_start = time.time()
+ if dist.get_rank() == 0:
+ save_model(
+ model,
+ optimizer,
+ save_model_dir,
+ logger,
+ config,
+ is_best=False,
+ prefix='latest',
+ best_model_dict=best_model_dict,
+ epoch=epoch,
+ global_step=global_step)
+
+ if log_writer is not None:
+ log_writer.log_model(is_best=False, prefix="latest")
+
+ if dist.get_rank() == 0 and epoch > 0 and epoch % save_epoch_step == 0:
+ save_model(
+ model,
+ optimizer,
+ save_model_dir,
+ logger,
+ config,
+ is_best=False,
+ prefix='iter_epoch_{}'.format(epoch),
+ best_model_dict=best_model_dict,
+ epoch=epoch,
+ global_step=global_step)
+ if log_writer is not None:
+ log_writer.log_model(
+ is_best=False, prefix='iter_epoch_{}'.format(epoch))
+
+ best_str = 'best metric, {}'.format(', '.join(
+ ['{}: {}'.format(k, v) for k, v in best_model_dict.items()]))
+ logger.info(best_str)
+ if dist.get_rank() == 0 and log_writer is not None:
+ log_writer.close()
+ return
+
+
+def eval(model,
+ valid_dataloader,
+ post_process_class,
+ eval_class,
+ model_type=None,
+ extra_input=False,
+ scaler=None,
+ amp_level='O2',
+ amp_custom_black_list=[],
+ amp_custom_white_list=[],
+ amp_dtype='float16'):
+ model.eval()
+ with paddle.no_grad():
+ total_frame = 0.0
+ total_time = 0.0
+ pbar = tqdm(
+ total=len(valid_dataloader),
+ desc='eval model:',
+ position=0,
+ leave=True)
+ max_iter = len(valid_dataloader) - 1 if platform.system(
+ ) == "Windows" else len(valid_dataloader)
+ sum_images = 0
+ for idx, batch in enumerate(valid_dataloader):
+ if idx >= max_iter:
+ break
+ images = batch[0]
+ start = time.time()
+
+ # use amp
+ if scaler:
+ with paddle.amp.auto_cast(
+ level=amp_level,
+ custom_black_list=amp_custom_black_list,
+ dtype=amp_dtype):
+ if model_type == 'table' or extra_input:
+ preds = model(images, data=batch[1:])
+ elif model_type in ["kie"]:
+ preds = model(batch)
+ elif model_type in ['can']:
+ preds = model(batch[:3])
+ elif model_type in ['sr']:
+ preds = model(batch)
+ sr_img = preds["sr_img"]
+ lr_img = preds["lr_img"]
+ else:
+ preds = model(images)
+ preds = to_float32(preds)
+ else:
+ if model_type == 'table' or extra_input:
+ preds = model(images, data=batch[1:])
+ elif model_type in ["kie"]:
+ preds = model(batch)
+ elif model_type in ['can']:
+ preds = model(batch[:3])
+ elif model_type in ['sr']:
+ preds = model(batch)
+ sr_img = preds["sr_img"]
+ lr_img = preds["lr_img"]
+ else:
+ preds = model(images)
+
+ batch_numpy = []
+ for item in batch:
+ if isinstance(item, paddle.Tensor):
+ batch_numpy.append(item.numpy())
+ else:
+ batch_numpy.append(item)
+ # Obtain usable results from post-processing methods
+ total_time += time.time() - start
+ # Evaluate the results of the current batch
+ if model_type in ['table', 'kie']:
+ if post_process_class is None:
+ eval_class(preds, batch_numpy)
+ else:
+ post_result = post_process_class(preds, batch_numpy)
+ eval_class(post_result, batch_numpy)
+ elif model_type in ['sr']:
+ eval_class(preds, batch_numpy)
+ elif model_type in ['can']:
+ eval_class(preds[0], batch_numpy[2:], epoch_reset=(idx == 0))
+ else:
+ post_result = post_process_class(preds, batch_numpy[1])
+ eval_class(post_result, batch_numpy)
+
+ pbar.update(1)
+ total_frame += len(images)
+ sum_images += 1
+ # Get final metric,eg. acc or hmean
+ metric = eval_class.get_metric()
+
+ pbar.close()
+ model.train()
+ metric['fps'] = total_frame / total_time
+ return metric
+
+
+def update_center(char_center, post_result, preds):
+ result, label = post_result
+ feats, logits = preds
+ logits = paddle.argmax(logits, axis=-1)
+ feats = feats.numpy()
+ logits = logits.numpy()
+
+ for idx_sample in range(len(label)):
+ if result[idx_sample][0] == label[idx_sample][0]:
+ feat = feats[idx_sample]
+ logit = logits[idx_sample]
+ for idx_time in range(len(logit)):
+ index = logit[idx_time]
+ if index in char_center.keys():
+ char_center[index][0] = (
+ char_center[index][0] * char_center[index][1] +
+ feat[idx_time]) / (char_center[index][1] + 1)
+ char_center[index][1] += 1
+ else:
+ char_center[index] = [feat[idx_time], 1]
+ return char_center
+
+
+def get_center(model, eval_dataloader, post_process_class):
+ pbar = tqdm(total=len(eval_dataloader), desc='get center:')
+ max_iter = len(eval_dataloader) - 1 if platform.system(
+ ) == "Windows" else len(eval_dataloader)
+ char_center = dict()
+ for idx, batch in enumerate(eval_dataloader):
+ if idx >= max_iter:
+ break
+ images = batch[0]
+ start = time.time()
+ preds = model(images)
+
+ batch = [item.numpy() for item in batch]
+ # Obtain usable results from post-processing methods
+ post_result = post_process_class(preds, batch[1])
+
+ #update char_center
+ char_center = update_center(char_center, post_result, preds)
+ pbar.update(1)
+
+ pbar.close()
+ for key in char_center.keys():
+ char_center[key] = char_center[key][0]
+ return char_center
+
+
+def preprocess(is_train=False):
+ FLAGS = ArgsParser().parse_args()
+ profiler_options = FLAGS.profiler_options
+ config = load_config(FLAGS.config)
+ config = merge_config(config, FLAGS.opt)
+ profile_dic = {"profiler_options": FLAGS.profiler_options}
+ config = merge_config(config, profile_dic)
+
+ if is_train:
+ # save_config
+ save_model_dir = config['Global']['save_model_dir']
+ os.makedirs(save_model_dir, exist_ok=True)
+ with open(os.path.join(save_model_dir, 'config.yml'), 'w') as f:
+ yaml.dump(
+ dict(config), f, default_flow_style=False, sort_keys=False)
+ log_file = '{}/train.log'.format(save_model_dir)
+ else:
+ log_file = None
+ logger = get_logger(log_file=log_file)
+
+ # check if set use_gpu=True in paddlepaddle cpu version
+ use_gpu = config['Global'].get('use_gpu', False)
+ use_xpu = config['Global'].get('use_xpu', False)
+ use_npu = config['Global'].get('use_npu', False)
+ use_mlu = config['Global'].get('use_mlu', False)
+
+ alg = config['Architecture']['algorithm']
+ assert alg in [
+ 'EAST', 'DB', 'SAST', 'Rosetta', 'CRNN', 'STARNet', 'RARE', 'SRN',
+ 'CLS', 'PGNet', 'Distillation', 'NRTR', 'TableAttn', 'SAR', 'PSE',
+ 'SEED', 'SDMGR', 'LayoutXLM', 'LayoutLM', 'LayoutLMv2', 'PREN', 'FCE',
+ 'SVTR', 'SVTR_LCNet', 'ViTSTR', 'ABINet', 'DB++', 'TableMaster', 'SPIN',
+ 'VisionLAN', 'Gestalt', 'SLANet', 'RobustScanner', 'CT', 'RFL', 'DRRG',
+ 'CAN', 'Telescope', 'SATRN', 'SVTR_HGNet', 'ParseQ', 'CPPD'
+ ]
+
+ if use_xpu:
+ device = 'xpu:{0}'.format(os.getenv('FLAGS_selected_xpus', 0))
+ elif use_npu:
+ device = 'npu:{0}'.format(os.getenv('FLAGS_selected_npus', 0))
+ elif use_mlu:
+ device = 'mlu:{0}'.format(os.getenv('FLAGS_selected_mlus', 0))
+ else:
+ device = 'gpu:{}'.format(dist.ParallelEnv()
+ .dev_id) if use_gpu else 'cpu'
+ check_device(use_gpu, use_xpu, use_npu, use_mlu)
+
+ device = paddle.set_device(device)
+
+ config['Global']['distributed'] = dist.get_world_size() != 1
+
+ loggers = []
+
+ if 'use_visualdl' in config['Global'] and config['Global']['use_visualdl']:
+ save_model_dir = config['Global']['save_model_dir']
+ vdl_writer_path = save_model_dir
+ log_writer = VDLLogger(vdl_writer_path)
+ loggers.append(log_writer)
+ if ('use_wandb' in config['Global'] and
+ config['Global']['use_wandb']) or 'wandb' in config:
+ save_dir = config['Global']['save_model_dir']
+ wandb_writer_path = "{}/wandb".format(save_dir)
+ if "wandb" in config:
+ wandb_params = config['wandb']
+ else:
+ wandb_params = dict()
+ wandb_params.update({'save_dir': save_dir})
+ log_writer = WandbLogger(**wandb_params, config=config)
+ loggers.append(log_writer)
+ else:
+ log_writer = None
+ print_dict(config, logger)
+
+ if loggers:
+ log_writer = Loggers(loggers)
+ else:
+ log_writer = None
+
+ logger.info('train with paddle {} and device {}'.format(paddle.__version__,
+ device))
+ return config, device, logger, log_writer
diff --git a/ocr-studio/PaddleOCR/tools/resolve_doc_github_refs.py b/ocr-studio/PaddleOCR/tools/resolve_doc_github_refs.py
new file mode 100644
index 0000000000000000000000000000000000000000..b7eea1ef71fa1adf9b2806ae70c903987dcd80e2
--- /dev/null
+++ b/ocr-studio/PaddleOCR/tools/resolve_doc_github_refs.py
@@ -0,0 +1,49 @@
+#!/usr/bin/env python3
+import argparse
+from pathlib import Path
+
+
+TEXT_SUFFIXES = {".md", ".yml", ".yaml"}
+
+
+def resolve_placeholders(root, placeholder, source_ref):
+ if (
+ not source_ref
+ or source_ref.strip() != source_ref
+ or any(c.isspace() for c in source_ref)
+ ):
+ raise ValueError("source_ref must be a non-empty ref without whitespace")
+
+ root = Path(root)
+ changed = []
+ for path in sorted(root.rglob("*")):
+ if not path.is_file() or path.suffix not in TEXT_SUFFIXES:
+ continue
+ content = path.read_text(encoding="utf-8")
+ if placeholder not in content:
+ continue
+ path.write_text(content.replace(placeholder, source_ref), encoding="utf-8")
+ changed.append(path)
+ return changed
+
+
+def main(argv=None):
+ parser = argparse.ArgumentParser(
+ description="Resolve docs GitHub source-ref placeholders before building docs."
+ )
+ parser.add_argument("--root", default="docs", help="Directory to rewrite.")
+ parser.add_argument("--placeholder", required=True)
+ parser.add_argument("--source-ref", required=True)
+ args = parser.parse_args(argv)
+
+ changed = resolve_placeholders(
+ args.root,
+ placeholder=args.placeholder,
+ source_ref=args.source_ref,
+ )
+ print(f"Resolved {len(changed)} file(s) under {args.root}.")
+ return 0
+
+
+if __name__ == "__main__":
+ raise SystemExit(main())
diff --git a/ocr-studio/PaddleOCR/tools/test_hubserving.py b/ocr-studio/PaddleOCR/tools/test_hubserving.py
new file mode 100644
index 0000000000000000000000000000000000000000..ec17a9413e15b3ae92843990cfcbb05fc5f991a8
--- /dev/null
+++ b/ocr-studio/PaddleOCR/tools/test_hubserving.py
@@ -0,0 +1,157 @@
+# Copyright (c) 2020 PaddlePaddle Authors. All Rights Reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+import os
+import sys
+__dir__ = os.path.dirname(os.path.abspath(__file__))
+sys.path.append(__dir__)
+sys.path.append(os.path.abspath(os.path.join(__dir__, '..')))
+
+from ppocr.utils.logging import get_logger
+logger = get_logger()
+
+import cv2
+import numpy as np
+import time
+from PIL import Image
+from ppocr.utils.utility import get_image_file_list
+from tools.infer.utility import draw_ocr, draw_boxes, str2bool
+from ppstructure.utility import draw_structure_result
+from ppstructure.predict_system import to_excel
+
+import requests
+import json
+import base64
+
+
+def cv2_to_base64(image):
+ return base64.b64encode(image).decode('utf8')
+
+
+def draw_server_result(image_file, res):
+ img = cv2.imread(image_file)
+ image = Image.fromarray(cv2.cvtColor(img, cv2.COLOR_BGR2RGB))
+ if len(res) == 0:
+ return np.array(image)
+ keys = res[0].keys()
+ if 'text_region' not in keys: # for ocr_rec, draw function is invalid
+ logger.info("draw function is invalid for ocr_rec!")
+ return None
+ elif 'text' not in keys: # for ocr_det
+ logger.info("draw text boxes only!")
+ boxes = []
+ for dno in range(len(res)):
+ boxes.append(res[dno]['text_region'])
+ boxes = np.array(boxes)
+ draw_img = draw_boxes(image, boxes)
+ return draw_img
+ else: # for ocr_system
+ logger.info("draw boxes and texts!")
+ boxes = []
+ texts = []
+ scores = []
+ for dno in range(len(res)):
+ boxes.append(res[dno]['text_region'])
+ texts.append(res[dno]['text'])
+ scores.append(res[dno]['confidence'])
+ boxes = np.array(boxes)
+ scores = np.array(scores)
+ draw_img = draw_ocr(
+ image, boxes, texts, scores, draw_txt=True, drop_score=0.5)
+ return draw_img
+
+
+def save_structure_res(res, save_folder, image_file):
+ img = cv2.imread(image_file)
+ excel_save_folder = os.path.join(save_folder, os.path.basename(image_file))
+ os.makedirs(excel_save_folder, exist_ok=True)
+ # save res
+ with open(
+ os.path.join(excel_save_folder, 'res.txt'), 'w',
+ encoding='utf8') as f:
+ for region in res:
+ if region['type'] == 'Table':
+ excel_path = os.path.join(excel_save_folder,
+ '{}.xlsx'.format(region['bbox']))
+ to_excel(region['res'], excel_path)
+ elif region['type'] == 'Figure':
+ x1, y1, x2, y2 = region['bbox']
+ print(region['bbox'])
+ roi_img = img[y1:y2, x1:x2, :]
+ img_path = os.path.join(excel_save_folder,
+ '{}.jpg'.format(region['bbox']))
+ cv2.imwrite(img_path, roi_img)
+ else:
+ for text_result in region['res']:
+ f.write('{}\n'.format(json.dumps(text_result)))
+
+
+def main(args):
+ image_file_list = get_image_file_list(args.image_dir)
+ is_visualize = False
+ headers = {"Content-type": "application/json"}
+ cnt = 0
+ total_time = 0
+ for image_file in image_file_list:
+ img = open(image_file, 'rb').read()
+ if img is None:
+ logger.info("error in loading image:{}".format(image_file))
+ continue
+ img_name = os.path.basename(image_file)
+ # seed http request
+ starttime = time.time()
+ data = {'images': [cv2_to_base64(img)]}
+ r = requests.post(
+ url=args.server_url, headers=headers, data=json.dumps(data))
+ elapse = time.time() - starttime
+ total_time += elapse
+ logger.info("Predict time of %s: %.3fs" % (image_file, elapse))
+ res = r.json()["results"][0]
+ logger.info(res)
+
+ if args.visualize:
+ draw_img = None
+ if 'structure_table' in args.server_url:
+ to_excel(res['html'], './{}.xlsx'.format(img_name))
+ elif 'structure_system' in args.server_url:
+ save_structure_res(res['regions'], args.output, image_file)
+ else:
+ draw_img = draw_server_result(image_file, res)
+ if draw_img is not None:
+ if not os.path.exists(args.output):
+ os.makedirs(args.output)
+ cv2.imwrite(
+ os.path.join(args.output, os.path.basename(image_file)),
+ draw_img[:, :, ::-1])
+ logger.info("The visualized image saved in {}".format(
+ os.path.join(args.output, os.path.basename(image_file))))
+ cnt += 1
+ if cnt % 100 == 0:
+ logger.info("{} processed".format(cnt))
+ logger.info("avg time cost: {}".format(float(total_time) / cnt))
+
+
+def parse_args():
+ import argparse
+ parser = argparse.ArgumentParser(description="args for hub serving")
+ parser.add_argument("--server_url", type=str, required=True)
+ parser.add_argument("--image_dir", type=str, required=True)
+ parser.add_argument("--visualize", type=str2bool, default=False)
+ parser.add_argument("--output", type=str, default='./hubserving_result')
+ args = parser.parse_args()
+ return args
+
+
+if __name__ == '__main__':
+ args = parse_args()
+ main(args)
diff --git a/ocr-studio/PaddleOCR/tools/train.py b/ocr-studio/PaddleOCR/tools/train.py
new file mode 100644
index 0000000000000000000000000000000000000000..faed388ec13d34bf57c186481980aa069af2ac5d
--- /dev/null
+++ b/ocr-studio/PaddleOCR/tools/train.py
@@ -0,0 +1,230 @@
+# Copyright (c) 2020 PaddlePaddle Authors. All Rights Reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+from __future__ import absolute_import
+from __future__ import division
+from __future__ import print_function
+
+import os
+import sys
+
+__dir__ = os.path.dirname(os.path.abspath(__file__))
+sys.path.append(__dir__)
+sys.path.insert(0, os.path.abspath(os.path.join(__dir__, '..')))
+
+import yaml
+import paddle
+import paddle.distributed as dist
+
+from ppocr.data import build_dataloader, set_signal_handlers
+from ppocr.modeling.architectures import build_model
+from ppocr.losses import build_loss
+from ppocr.optimizer import build_optimizer
+from ppocr.postprocess import build_post_process
+from ppocr.metrics import build_metric
+from ppocr.utils.save_load import load_model
+from ppocr.utils.utility import set_seed
+from ppocr.modeling.architectures import apply_to_static
+import tools.program as program
+
+dist.get_world_size()
+
+
+def main(config, device, logger, vdl_writer, seed):
+ # init dist environment
+ if config['Global']['distributed']:
+ dist.init_parallel_env()
+
+ global_config = config['Global']
+
+ # build dataloader
+ set_signal_handlers()
+ train_dataloader = build_dataloader(config, 'Train', device, logger, seed)
+ if len(train_dataloader) == 0:
+ logger.error(
+ "No Images in train dataset, please ensure\n" +
+ "\t1. The images num in the train label_file_list should be larger than or equal with batch size.\n"
+ +
+ "\t2. The annotation file and path in the configuration file are provided normally."
+ )
+ return
+
+ if config['Eval']:
+ valid_dataloader = build_dataloader(config, 'Eval', device, logger,
+ seed)
+ else:
+ valid_dataloader = None
+ step_pre_epoch = len(train_dataloader)
+
+ # build post process
+ post_process_class = build_post_process(config['PostProcess'],
+ global_config)
+
+ # build model
+ # for rec algorithm
+ if hasattr(post_process_class, 'character'):
+ char_num = len(getattr(post_process_class, 'character'))
+ if config['Architecture']["algorithm"] in ["Distillation",
+ ]: # distillation model
+ for key in config['Architecture']["Models"]:
+ if config['Architecture']['Models'][key]['Head'][
+ 'name'] == 'MultiHead': # for multi head
+ if config['PostProcess'][
+ 'name'] == 'DistillationSARLabelDecode':
+ char_num = char_num - 2
+ if config['PostProcess'][
+ 'name'] == 'DistillationNRTRLabelDecode':
+ char_num = char_num - 3
+ out_channels_list = {}
+ out_channels_list['CTCLabelDecode'] = char_num
+ # update SARLoss params
+ if list(config['Loss']['loss_config_list'][-1].keys())[
+ 0] == 'DistillationSARLoss':
+ config['Loss']['loss_config_list'][-1][
+ 'DistillationSARLoss'][
+ 'ignore_index'] = char_num + 1
+ out_channels_list['SARLabelDecode'] = char_num + 2
+ elif any('DistillationNRTRLoss' in d
+ for d in config['Loss']['loss_config_list']):
+ out_channels_list['NRTRLabelDecode'] = char_num + 3
+
+ config['Architecture']['Models'][key]['Head'][
+ 'out_channels_list'] = out_channels_list
+ else:
+ config['Architecture']["Models"][key]["Head"][
+ 'out_channels'] = char_num
+ elif config['Architecture']['Head'][
+ 'name'] == 'MultiHead': # for multi head
+ if config['PostProcess']['name'] == 'SARLabelDecode':
+ char_num = char_num - 2
+ if config['PostProcess']['name'] == 'NRTRLabelDecode':
+ char_num = char_num - 3
+ out_channels_list = {}
+ out_channels_list['CTCLabelDecode'] = char_num
+ # update SARLoss params
+ if list(config['Loss']['loss_config_list'][1].keys())[
+ 0] == 'SARLoss':
+ if config['Loss']['loss_config_list'][1]['SARLoss'] is None:
+ config['Loss']['loss_config_list'][1]['SARLoss'] = {
+ 'ignore_index': char_num + 1
+ }
+ else:
+ config['Loss']['loss_config_list'][1]['SARLoss'][
+ 'ignore_index'] = char_num + 1
+ out_channels_list['SARLabelDecode'] = char_num + 2
+ elif list(config['Loss']['loss_config_list'][1].keys())[
+ 0] == 'NRTRLoss':
+ out_channels_list['NRTRLabelDecode'] = char_num + 3
+ config['Architecture']['Head'][
+ 'out_channels_list'] = out_channels_list
+ else: # base rec model
+ config['Architecture']["Head"]['out_channels'] = char_num
+
+ if config['PostProcess']['name'] == 'SARLabelDecode': # for SAR model
+ config['Loss']['ignore_index'] = char_num - 1
+
+ model = build_model(config['Architecture'])
+
+ use_sync_bn = config["Global"].get("use_sync_bn", False)
+ if use_sync_bn:
+ model = paddle.nn.SyncBatchNorm.convert_sync_batchnorm(model)
+ logger.info('convert_sync_batchnorm')
+
+ model = apply_to_static(model, config, logger)
+
+ # build loss
+ loss_class = build_loss(config['Loss'])
+
+ # build optim
+ optimizer, lr_scheduler = build_optimizer(
+ config['Optimizer'],
+ epochs=config['Global']['epoch_num'],
+ step_each_epoch=len(train_dataloader),
+ model=model)
+
+ # build metric
+ eval_class = build_metric(config['Metric'])
+
+ logger.info('train dataloader has {} iters'.format(len(train_dataloader)))
+ if valid_dataloader is not None:
+ logger.info('valid dataloader has {} iters'.format(
+ len(valid_dataloader)))
+
+ use_amp = config["Global"].get("use_amp", False)
+ amp_level = config["Global"].get("amp_level", 'O2')
+ amp_dtype = config["Global"].get("amp_dtype", 'float16')
+ amp_custom_black_list = config['Global'].get('amp_custom_black_list', [])
+ amp_custom_white_list = config['Global'].get('amp_custom_white_list', [])
+ if use_amp:
+ AMP_RELATED_FLAGS_SETTING = {'FLAGS_max_inplace_grad_add': 8, }
+ if paddle.is_compiled_with_cuda():
+ AMP_RELATED_FLAGS_SETTING.update({
+ 'FLAGS_cudnn_batchnorm_spatial_persistent': 1,
+ 'FLAGS_gemm_use_half_precision_compute_type': 0,
+ })
+ paddle.set_flags(AMP_RELATED_FLAGS_SETTING)
+ scale_loss = config["Global"].get("scale_loss", 1.0)
+ use_dynamic_loss_scaling = config["Global"].get(
+ "use_dynamic_loss_scaling", False)
+ scaler = paddle.amp.GradScaler(
+ init_loss_scaling=scale_loss,
+ use_dynamic_loss_scaling=use_dynamic_loss_scaling)
+ if amp_level == "O2":
+ model, optimizer = paddle.amp.decorate(
+ models=model,
+ optimizers=optimizer,
+ level=amp_level,
+ master_weight=True,
+ dtype=amp_dtype)
+ else:
+ scaler = None
+
+ # load pretrain model
+ pre_best_model_dict = load_model(config, model, optimizer,
+ config['Architecture']["model_type"])
+
+ if config['Global']['distributed']:
+ model = paddle.DataParallel(model)
+ # start train
+ program.train(config, train_dataloader, valid_dataloader, device, model,
+ loss_class, optimizer, lr_scheduler, post_process_class,
+ eval_class, pre_best_model_dict, logger, step_pre_epoch,
+ vdl_writer, scaler, amp_level, amp_custom_black_list,
+ amp_custom_white_list, amp_dtype)
+
+
+def test_reader(config, device, logger):
+ loader = build_dataloader(config, 'Train', device, logger)
+ import time
+ starttime = time.time()
+ count = 0
+ try:
+ for data in loader():
+ count += 1
+ if count % 1 == 0:
+ batch_time = time.time() - starttime
+ starttime = time.time()
+ logger.info("reader: {}, {}, {}".format(
+ count, len(data[0]), batch_time))
+ except Exception as e:
+ logger.info(e)
+ logger.info("finish reader: {}, Success!".format(count))
+
+
+if __name__ == '__main__':
+ config, device, logger, vdl_writer = program.preprocess(is_train=True)
+ seed = config['Global']['seed'] if 'seed' in config['Global'] else 1024
+ set_seed(seed)
+ main(config, device, logger, vdl_writer, seed)
+ # test_reader(config, device, logger)
diff --git a/ocr-studio/PaddleOCR/train.sh b/ocr-studio/PaddleOCR/train.sh
new file mode 100644
index 0000000000000000000000000000000000000000..6fa04ea3febe8982016a35d83f119c0a483e3bb8
--- /dev/null
+++ b/ocr-studio/PaddleOCR/train.sh
@@ -0,0 +1,2 @@
+# recommended paddle.__version__ == 2.0.0
+python3 -m paddle.distributed.launch --log_dir=./debug/ --gpus '0,1,2,3,4,5,6,7' tools/train.py -c configs/rec/rec_mv3_none_bilstm_ctc.yml
\ No newline at end of file
diff --git a/ocr-studio/README_STUDIO.md b/ocr-studio/README_STUDIO.md
new file mode 100644
index 0000000000000000000000000000000000000000..3060fa7b7d9592f63f1fcfdbfff748c2028f1975
--- /dev/null
+++ b/ocr-studio/README_STUDIO.md
@@ -0,0 +1,57 @@
+# Cham OCR Diagnostic Studio (OCR Review & Inference Studio)
+
+Ứng dụng này cung cấp giao diện web cục bộ để thử nghiệm, chẩn đoán lỗi phân đoạn dòng (Line Segmentation) và kiểm tra độ chính xác của các mô hình nhận diện chữ viết tiếng Chăm khác nhau.
+
+## 📁 Cấu trúc Thư mục Phân hệ Studio
+
+```
+ocr-studio/
+├── README_STUDIO.md # Hướng dẫn này
+├── app.py # Script chạy ứng dụng Web Server & Studio Backend
+├── index.html # Frontend Claude Warm Light Theme
+├── start_studio.py # Script khởi động nhanh giao diện
+├── PaddleOCR/ # Bản sao thư viện PaddleOCR phục vụ suy luận cục bộ
+└── data/ # Dữ liệu phục vụ suy luận
+ ├── ocr_corrections.txt # Lưu trữ các chỉnh sửa nhãn của người dùng
+ ├── cham_dict_v*.txt # Từ điển ký tự các phiên bản mô hình
+ └── output/ # Thư mục chứa các mô hình nhận diện đã xuất (inference model)
+ ├── rec_cham_inference_v18/
+ ├── rec_cham_inference_v21/
+ ├── rec_cham_inference_v22/
+ └── rec_cham_inference_v23/
+```
+
+---
+
+## ⚡ Yêu cầu hệ thống & Cài đặt
+
+1. Cài đặt các thư viện cần thiết từ thư mục gốc:
+ ```bash
+ pip install -r requirements.txt
+ ```
+ *Lưu ý*: Đối với môi trường Python mới (như Python 3.13+), ứng dụng đã tự động vá lỗi tương thích NumPy 2.x bằng monkeypatch.
+
+2. Đảm bảo bạn đã có các mô hình inference trong `ocr-studio/data/output/` và file từ điển tương ứng trong `ocr-studio/data/`.
+
+---
+
+## 🚀 Hướng dẫn khởi chạy
+
+Chạy lệnh sau tại thư mục gốc của dự án hoặc trong thư mục `ocr-studio`:
+
+```bash
+python ocr-studio/app.py
+```
+
+Hoặc sử dụng tệp khởi chạy nhanh:
+```bash
+python ocr-studio/start_studio.py
+```
+
+Ứng dụng sẽ tìm kiếm cổng trống thích hợp (mặc định: `7860`, `8080`, `8081`...) và khởi chạy:
+```
+🚀 Cham OCR Diagnostic Studio is running at: http://localhost:7860
+📁 Corrections will be saved to: ocr-studio/data/ocr_corrections.txt
+```
+
+Mở trình duyệt và truy cập `http://localhost:7860` để bắt đầu kiểm tra chẩn đoán ảnh chữ viết tiếng Chăm.
diff --git a/ocr-studio/start_studio.py b/ocr-studio/start_studio.py
new file mode 100644
index 0000000000000000000000000000000000000000..949ef90a877e2f2acc6a2135d1e70708a300af90
--- /dev/null
+++ b/ocr-studio/start_studio.py
@@ -0,0 +1,24 @@
+import subprocess
+import sys
+import os
+
+# Get path of ocr-studio directory
+PROJECT_ROOT = os.path.dirname(os.path.abspath(__file__))
+app_path = os.path.join(PROJECT_ROOT, "app.py")
+
+# Environment settings to prevent OpenMP deadlocks on Windows
+env = os.environ.copy()
+env["CPU_THREADS"] = "1"
+env["ENABLE_MKLDNN"] = "False"
+env["OMP_NUM_THREADS"] = "1"
+env["MKL_NUM_THREADS"] = "1"
+env["KMP_DUPLICATE_LIB_OK"] = "TRUE"
+
+print("Starting Cham OCR Studio in a new clean console window...")
+subprocess.Popen(
+ [sys.executable, "-u", app_path],
+ cwd=os.path.dirname(PROJECT_ROOT), # Run from workspace root to match relative paths
+ env=env,
+ creationflags=subprocess.CREATE_NEW_CONSOLE
+)
+print("Cham OCR Studio launched successfully in a separate desktop window.")
 +
 +

 +
 +


 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +