```yaml
license: cc-by-nc-sa-4.0
language:
- en
tags:
- relighting
- multi-view
- generative-transformer
- 3d-vision
- siggraph-asia-2026
- wan2.1
pipeline_tag: image-to-image
```
🔆 RelightFormer
Feed-Forward Generative Transformer for Multiview Object Relighting
vLAR Group | SIGGRAPH Asia 2026


## 🌟 Overview
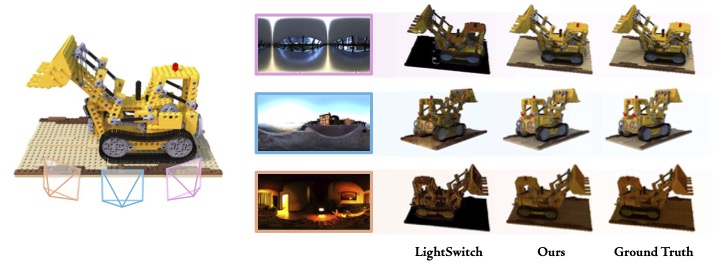
**RelightFormer** revolutionizes image relighting by replacing traditional, computationally expensive inverse rendering with a feed-forward generative Transformer. By seamlessly injecting target lighting into spatial features and processing multiple views symmetrically, it delivers highly photorealistic results. Trained on the newly introduced, large-scale open-source **Laval-Objaverse Dataset (LOD )**, RelightFormer achieves state-of-the-art quality and remarkable generalization across diverse scenes.
### ✨ Key Features
- 🏹 **Feed-Forward Architecture**: No iterative optimization required, enabling rapid generation.
- 🌟 **Multi-View Consistency**: Coherent and physically plausible relighting across all viewpoints.
- ⚡ **Performant Inference**: Highly optimized and expeditious execution on modern GPUs.
- 🎨 **Competitive Quality**: State-of-the-art, photorealistic relighting results.
---
## 🚀 Quick Start
You can easily load and run the model using the `diffsynth` library in our [GitHub Repository](https://github.com/vLAR-group/RelightFormer).
We provide two revisions: `main` (RelightFormer) and `post` (RelightFormer-Post, fine-tuned for enhanced quality).
```python
from diffsynth import RelightFormerPipeline
# Use revision='main' for RelightFormer, or 'post' for RelightFormer-Post
pipe = RelightFormerPipeline.from_pretrained(
"vLAR/RelightFormer",
revision="main"
)
# Example inference (adjust inputs according to your specific pipeline API)
# output = pipe(image=..., lighting=..., ...)
```
> 💡 **For full inference scripts, multi-GPU evaluation, and training code, please visit the **[**Official GitHub Repository**](https://github.com/vLAR-group/RelightFormer)**.**
---
## 📦 Dataset
This model is trained on the **Laval-Objaverse Dataset (LOD)**, comprising **90,545 high-quality 3D assets** and **39,008 diverse illumination conditions**.
- 🤗 **Browse/Download the Dataset**: [vLAR/LavalObjaverseDataset](https://huggingface.co/datasets/vLAR/LavalObjaverseDataset)
- 📖 **Rendering Instructions**: See the [`RENDERING_INSTRUCTION.md`](https://github.com/vLAR-group/RelightFormer/blob/main/laval-objaverse-dataset/RENDERING_INSTRUCTION.md) in the GitHub repo.
---
## 🏋️ Training Details
RelightFormer is fine-tuned from the **Wan 2.1** base model. The training pipeline consists of two stages:
1. **Main Training**: Trained on the full LOD dataset to learn multi-view relighting priors.
1. **Post-Training**: A secondary fine-tuning stage to further enhance photorealism and consistency.
Detailed training configurations, hardware requirements (e.g., 4× H200 GPUs), and scripts are available in the [GitHub Repository](https://github.com/vLAR-group/RelightFormer).
---
## 📜 License
This model, its code, and associated datasets are licensed under the [Creative Commons Attribution-NonCommercial-ShareAlike 4.0 International License](https://creativecommons.org/licenses/by-nc-sa/4.0/) (CC BY-NC-SA 4.0).
---
## 🙏 Acknowledgements
This work was supported in part by the National Natural Science Foundation of China, the Research Grants Council of Hong Kong, the Otto Poon Charitable Foundation Smart Cities Research Institute, the Research Center for Unmanned Autonomous Systems, and the PolyU Kunpeng & Ascend Technology Innovation Incubation Center, The Hong Kong Polytechnic University.