


Add files using upload-large-folder tool
Browse files- .gitattributes +3 -32
- MANIFEST.sha256 +36 -0
- README.md +46 -0
- data/retrieval_v1/train.jsonl +3 -0
- models/MiniLM-L6-H384-uncased/.gitattributes +16 -0
- models/MiniLM-L6-H384-uncased/README.md +7 -0
- models/MiniLM-L6-H384-uncased/config.json +24 -0
- models/MiniLM-L6-H384-uncased/flax_model.msgpack +3 -0
- models/MiniLM-L6-H384-uncased/pytorch_model.bin +3 -0
- models/MiniLM-L6-H384-uncased/special_tokens_map.json +1 -0
- models/MiniLM-L6-H384-uncased/tokenizer_config.json +1 -0
- models/MiniLM-L6-H384-uncased/vocab.txt +0 -0
- models/Qwen3-4B-Instruct-2507/.gitattributes +36 -0
- models/Qwen3-4B-Instruct-2507/LICENSE +202 -0
- models/Qwen3-4B-Instruct-2507/README.md +211 -0
- models/Qwen3-4B-Instruct-2507/config.json +30 -0
- models/Qwen3-4B-Instruct-2507/generation_config.json +13 -0
- models/Qwen3-4B-Instruct-2507/merges.txt +0 -0
- models/Qwen3-4B-Instruct-2507/model-00001-of-00003.safetensors +3 -0
- models/Qwen3-4B-Instruct-2507/model-00002-of-00003.safetensors +3 -0
- models/Qwen3-4B-Instruct-2507/model-00003-of-00003.safetensors +3 -0
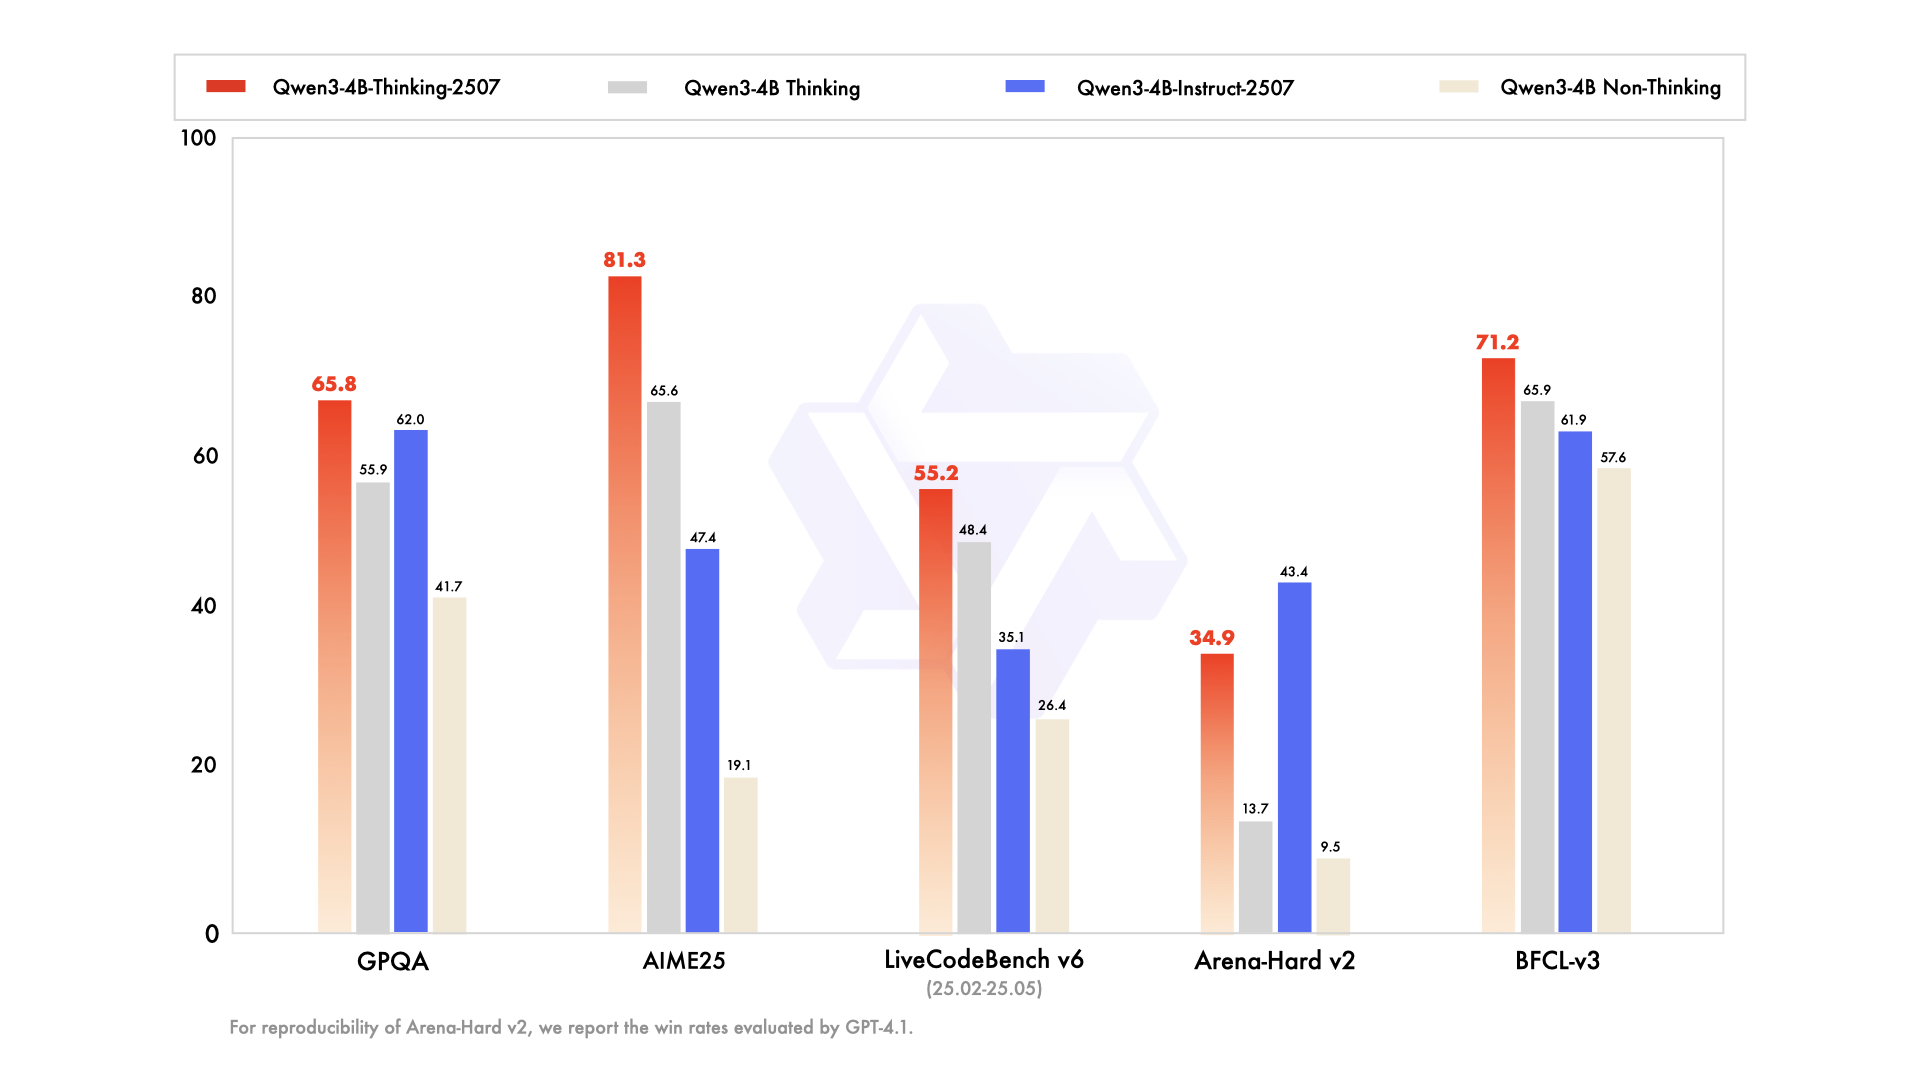
- models/Qwen3-4B-Instruct-2507/model.safetensors.index.json +405 -0
- models/Qwen3-4B-Instruct-2507/tokenizer.json +3 -0
- models/Qwen3-4B-Instruct-2507/tokenizer_config.json +239 -0
- models/Qwen3-4B-Instruct-2507/vocab.json +0 -0
- models/Qwen3-Embedding-0.6B/.gitattributes +36 -0
- models/Qwen3-Embedding-0.6B/1_Pooling/config.json +10 -0
- models/Qwen3-Embedding-0.6B/README.md +292 -0
- models/Qwen3-Embedding-0.6B/config.json +30 -0
- models/Qwen3-Embedding-0.6B/config_sentence_transformers.json +8 -0
- models/Qwen3-Embedding-0.6B/generation_config.json +6 -0
- models/Qwen3-Embedding-0.6B/merges.txt +0 -0
- models/Qwen3-Embedding-0.6B/model.safetensors +3 -0
- models/Qwen3-Embedding-0.6B/modules.json +20 -0
- models/Qwen3-Embedding-0.6B/tokenizer.json +3 -0
- models/Qwen3-Embedding-0.6B/tokenizer_config.json +240 -0
- models/Qwen3-Embedding-0.6B/vocab.json +0 -0
.gitattributes
CHANGED
|
@@ -1,35 +1,6 @@
|
|
| 1 |
-
*.7z filter=lfs diff=lfs merge=lfs -text
|
| 2 |
-
*.arrow filter=lfs diff=lfs merge=lfs -text
|
| 3 |
*.bin filter=lfs diff=lfs merge=lfs -text
|
| 4 |
-
*.
|
| 5 |
-
*.ckpt filter=lfs diff=lfs merge=lfs -text
|
| 6 |
-
*.ftz filter=lfs diff=lfs merge=lfs -text
|
| 7 |
-
*.gz filter=lfs diff=lfs merge=lfs -text
|
| 8 |
-
*.h5 filter=lfs diff=lfs merge=lfs -text
|
| 9 |
-
*.joblib filter=lfs diff=lfs merge=lfs -text
|
| 10 |
-
*.lfs.* filter=lfs diff=lfs merge=lfs -text
|
| 11 |
-
*.mlmodel filter=lfs diff=lfs merge=lfs -text
|
| 12 |
-
*.model filter=lfs diff=lfs merge=lfs -text
|
| 13 |
*.msgpack filter=lfs diff=lfs merge=lfs -text
|
| 14 |
-
*.npy filter=lfs diff=lfs merge=lfs -text
|
| 15 |
-
*.npz filter=lfs diff=lfs merge=lfs -text
|
| 16 |
-
*.onnx filter=lfs diff=lfs merge=lfs -text
|
| 17 |
-
*.ot filter=lfs diff=lfs merge=lfs -text
|
| 18 |
-
*.parquet filter=lfs diff=lfs merge=lfs -text
|
| 19 |
-
*.pb filter=lfs diff=lfs merge=lfs -text
|
| 20 |
-
*.pickle filter=lfs diff=lfs merge=lfs -text
|
| 21 |
-
*.pkl filter=lfs diff=lfs merge=lfs -text
|
| 22 |
-
*.pt filter=lfs diff=lfs merge=lfs -text
|
| 23 |
-
*.pth filter=lfs diff=lfs merge=lfs -text
|
| 24 |
-
*.rar filter=lfs diff=lfs merge=lfs -text
|
| 25 |
*.safetensors filter=lfs diff=lfs merge=lfs -text
|
| 26 |
-
|
| 27 |
-
|
| 28 |
-
*.tar filter=lfs diff=lfs merge=lfs -text
|
| 29 |
-
*.tflite filter=lfs diff=lfs merge=lfs -text
|
| 30 |
-
*.tgz filter=lfs diff=lfs merge=lfs -text
|
| 31 |
-
*.wasm filter=lfs diff=lfs merge=lfs -text
|
| 32 |
-
*.xz filter=lfs diff=lfs merge=lfs -text
|
| 33 |
-
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 34 |
-
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
-
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
|
|
|
|
|
|
|
|
|
| 1 |
*.bin filter=lfs diff=lfs merge=lfs -text
|
| 2 |
+
*.jsonl filter=lfs diff=lfs merge=lfs -text
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 3 |
*.msgpack filter=lfs diff=lfs merge=lfs -text
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 4 |
*.safetensors filter=lfs diff=lfs merge=lfs -text
|
| 5 |
+
models/Qwen3-4B-Instruct-2507/tokenizer.json filter=lfs diff=lfs merge=lfs -text
|
| 6 |
+
models/Qwen3-Embedding-0.6B/tokenizer.json filter=lfs diff=lfs merge=lfs -text
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
MANIFEST.sha256
ADDED
|
@@ -0,0 +1,36 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
5987d148a7a44ee29ff9fb3e8f041f817fa85eae14923fd5eb2ff005105d7b6a ./.gitattributes
|
| 2 |
+
6d7f65534043294e0db866e597d3be19b5b249f47164c969d22cf84e3796b3dd ./README.md
|
| 3 |
+
193d85660e80ed266376378655192a86655977bc46aaaf0980f7d28b1f29a3ab ./data/retrieval_v1/train.jsonl
|
| 4 |
+
98cf30ae2568ea1d18641cc0d1d9a2f9041cc43aea81f5d719654abd9e290e0d ./models/MiniLM-L6-H384-uncased/.gitattributes
|
| 5 |
+
4c0efe99b6adc8fac8ed3af25f7fcb81ce0e832bd4543158c39bdb6c65d2f63e ./models/MiniLM-L6-H384-uncased/README.md
|
| 6 |
+
cef11b3fb3c8f8e213025b03ffa238375381c153c5f6d09c3b69e7941cc1b8a9 ./models/MiniLM-L6-H384-uncased/config.json
|
| 7 |
+
cc64ec084e314b03470e11b4c5170bb9a64db946dc738768251ce188933dbab8 ./models/MiniLM-L6-H384-uncased/flax_model.msgpack
|
| 8 |
+
ab5048f3effe06bccb318ee923df90cba4e918b309a0ac6b00c654ede0768b87 ./models/MiniLM-L6-H384-uncased/pytorch_model.bin
|
| 9 |
+
303df45a03609e4ead04bc3dc1536d0ab19b5358db685b6f3da123d05ec200e3 ./models/MiniLM-L6-H384-uncased/special_tokens_map.json
|
| 10 |
+
004a73627dc426fe8178103267521ac79b8e9cb7442416a88996eafa52d51716 ./models/MiniLM-L6-H384-uncased/tokenizer_config.json
|
| 11 |
+
07eced375cec144d27c900241f3e339478dec958f92fddbc551f295c992038a3 ./models/MiniLM-L6-H384-uncased/vocab.txt
|
| 12 |
+
34448b82c17d60fec9b65b1f093c115ddbaadc04beb1b0140b6bfed2e012a930 ./models/Qwen3-4B-Instruct-2507/.gitattributes
|
| 13 |
+
832dd9e00a68dd83b3c3fb9f5588dad7dcf337a0db50f7d9483f310cd292e92e ./models/Qwen3-4B-Instruct-2507/LICENSE
|
| 14 |
+
8e3dd0c3b5b11897cc71092ccfe517bb7a9783479baa3665aad73c8d1a2041cd ./models/Qwen3-4B-Instruct-2507/README.md
|
| 15 |
+
5beea1a4a34c62782bfb2f911c606741a3bab8f92d80a118fa053c28af12e8ba ./models/Qwen3-4B-Instruct-2507/config.json
|
| 16 |
+
835fffe355c9438e7a25be099b3fccaa98350b83451f9fd2d99512e74f1ade48 ./models/Qwen3-4B-Instruct-2507/generation_config.json
|
| 17 |
+
599bab54075088774b1733fde865d5bd747cbcc7a547c5bc12610e874e26f5e3 ./models/Qwen3-4B-Instruct-2507/merges.txt
|
| 18 |
+
75311d91bb08cf0b882913da464a1e722a31fb44db35208663487efb7a3d8ed6 ./models/Qwen3-4B-Instruct-2507/model-00001-of-00003.safetensors
|
| 19 |
+
0b48adbb1f60e901153d91907ba11ce63bd4b8b584482e730f48808d055dfba1 ./models/Qwen3-4B-Instruct-2507/model-00002-of-00003.safetensors
|
| 20 |
+
7dd39ccca5e4de123c74c14af44c9bf2eb75df33b4614382af0134528e060d5d ./models/Qwen3-4B-Instruct-2507/model-00003-of-00003.safetensors
|
| 21 |
+
d6c42883a895dfef5b0080ed2116a1bcd764f558406b98923d675978a1abf29c ./models/Qwen3-4B-Instruct-2507/model.safetensors.index.json
|
| 22 |
+
aeb13307a71acd8fe81861d94ad54ab689df773318809eed3cbe794b4492dae4 ./models/Qwen3-4B-Instruct-2507/tokenizer.json
|
| 23 |
+
a62ff0a2472a0fa1b8eaabcb57c59b58afa42a22831dc141400b6e0cf2b65ce3 ./models/Qwen3-4B-Instruct-2507/tokenizer_config.json
|
| 24 |
+
ca10d7e9fb3ed18575dd1e277a2579c16d108e32f27439684afa0e10b1440910 ./models/Qwen3-4B-Instruct-2507/vocab.json
|
| 25 |
+
34448b82c17d60fec9b65b1f093c115ddbaadc04beb1b0140b6bfed2e012a930 ./models/Qwen3-Embedding-0.6B/.gitattributes
|
| 26 |
+
37bf193fa101f19101bfad9c31d3eb0f786e247b7b1e5cb7f007d730eed1ddbd ./models/Qwen3-Embedding-0.6B/1_Pooling/config.json
|
| 27 |
+
c34d9b7e5a267ad3fdd13227a253686bc90844ff4744a2a6a86c7c905e3d06f3 ./models/Qwen3-Embedding-0.6B/README.md
|
| 28 |
+
b5bf1f51fc45be473a54718cef92448d90a1be001bf9b9a44b8c7f10a19feaa9 ./models/Qwen3-Embedding-0.6B/config.json
|
| 29 |
+
10667c72ddb772627bf1780cb7f86af8e2ae0032b8c243c731172064105c6961 ./models/Qwen3-Embedding-0.6B/config_sentence_transformers.json
|
| 30 |
+
28396d421a2108acce96383f6a7de78008f7f1b17f807958f3c14c51dbfb65fb ./models/Qwen3-Embedding-0.6B/generation_config.json
|
| 31 |
+
8831e4f1a044471340f7c0a83d7bd71306a5b867e95fd870f74d0c5308a904d5 ./models/Qwen3-Embedding-0.6B/merges.txt
|
| 32 |
+
0437e45c94563b09e13cb7a64478fc406947a93cb34a7e05870fc8dcd48e23fd ./models/Qwen3-Embedding-0.6B/model.safetensors
|
| 33 |
+
84e40c8e006c9b1d6c122e02cba9b02458120b5fb0c87b746c41e0207cf642cf ./models/Qwen3-Embedding-0.6B/modules.json
|
| 34 |
+
def76fb086971c7867b829c23a26261e38d9d74e02139253b38aeb9df8b4b50a ./models/Qwen3-Embedding-0.6B/tokenizer.json
|
| 35 |
+
253153d0738ceb4c668d2eff957714dd2bea0b56de772a9fdccd96cbf517e6a0 ./models/Qwen3-Embedding-0.6B/tokenizer_config.json
|
| 36 |
+
ca10d7e9fb3ed18575dd1e277a2579c16d108e32f27439684afa0e10b1440910 ./models/Qwen3-Embedding-0.6B/vocab.json
|
README.md
ADDED
|
@@ -0,0 +1,46 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
---
|
| 2 |
+
pretty_name: AutoDataBench Retrieval Resources
|
| 3 |
+
tags:
|
| 4 |
+
- autodatabench
|
| 5 |
+
- information-retrieval
|
| 6 |
+
- sentence-transformers
|
| 7 |
+
---
|
| 8 |
+
|
| 9 |
+
# AutoDataBench Retrieval Resources
|
| 10 |
+
|
| 11 |
+
Resources for the retrieval task in
|
| 12 |
+
[AutoDataBench](https://github.com/AutoDataBench/AutoDataBench). See the
|
| 13 |
+
[paper](https://arxiv.org/abs/2609.40097) for the benchmark setting.
|
| 14 |
+
|
| 15 |
+
## Contents
|
| 16 |
+
|
| 17 |
+
```text
|
| 18 |
+
data/retrieval_v1/train.jsonl
|
| 19 |
+
models/MiniLM-L6-H384-uncased/
|
| 20 |
+
models/Qwen3-4B-Instruct-2507/
|
| 21 |
+
models/Qwen3-Embedding-0.6B/
|
| 22 |
+
```
|
| 23 |
+
|
| 24 |
+
`train.jsonl` is the 818,182-row source pool available to the data agent. Each
|
| 25 |
+
row contains `query`, `positive_doc`, `hard_negative_docs`, and `subset`.
|
| 26 |
+
|
| 27 |
+
| Model | Role | Original model |
|
| 28 |
+
| --- | --- | --- |
|
| 29 |
+
| MiniLM-L6-H384-uncased | Fixed retrieval base model | [nreimers/MiniLM-L6-H384-uncased](https://huggingface.co/nreimers/MiniLM-L6-H384-uncased) |
|
| 30 |
+
| Qwen3-4B-Instruct-2507 | Agent-callable generation model | [Qwen/Qwen3-4B-Instruct-2507](https://huggingface.co/Qwen/Qwen3-4B-Instruct-2507) |
|
| 31 |
+
| Qwen3-Embedding-0.6B | Agent-callable embedding model | [Qwen/Qwen3-Embedding-0.6B](https://huggingface.co/Qwen/Qwen3-Embedding-0.6B) |
|
| 32 |
+
|
| 33 |
+
The fixed and OOD evaluations use standard MTEB datasets, which are downloaded
|
| 34 |
+
by MTEB and are not duplicated here. The task configuration names the exact
|
| 35 |
+
evaluation suites.
|
| 36 |
+
|
| 37 |
+
## Use with AutoDataBench
|
| 38 |
+
|
| 39 |
+
Copy or symlink `data/` and `models/` into the AutoDataBench repository. The
|
| 40 |
+
default config refers to the auxiliary models by Hugging Face ID; point the
|
| 41 |
+
model servers at the local directories above for a fully local setup.
|
| 42 |
+
|
| 43 |
+
`MANIFEST.sha256` contains checksums for every distributed file.
|
| 44 |
+
|
| 45 |
+
Model and dataset components retain their upstream licenses. Consult the model
|
| 46 |
+
cards and source datasets before redistribution or commercial use.
|
data/retrieval_v1/train.jsonl
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:193d85660e80ed266376378655192a86655977bc46aaaf0980f7d28b1f29a3ab
|
| 3 |
+
size 527239276
|
models/MiniLM-L6-H384-uncased/.gitattributes
ADDED
|
@@ -0,0 +1,16 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
*.bin.* filter=lfs diff=lfs merge=lfs -text
|
| 2 |
+
*.lfs.* filter=lfs diff=lfs merge=lfs -text
|
| 3 |
+
*.bin filter=lfs diff=lfs merge=lfs -text
|
| 4 |
+
*.h5 filter=lfs diff=lfs merge=lfs -text
|
| 5 |
+
*.tflite filter=lfs diff=lfs merge=lfs -text
|
| 6 |
+
*.tar.gz filter=lfs diff=lfs merge=lfs -text
|
| 7 |
+
*.ot filter=lfs diff=lfs merge=lfs -text
|
| 8 |
+
*.onnx filter=lfs diff=lfs merge=lfs -text
|
| 9 |
+
*.arrow filter=lfs diff=lfs merge=lfs -text
|
| 10 |
+
*.ftz filter=lfs diff=lfs merge=lfs -text
|
| 11 |
+
*.joblib filter=lfs diff=lfs merge=lfs -text
|
| 12 |
+
*.model filter=lfs diff=lfs merge=lfs -text
|
| 13 |
+
*.msgpack filter=lfs diff=lfs merge=lfs -text
|
| 14 |
+
*.pb filter=lfs diff=lfs merge=lfs -text
|
| 15 |
+
*.pt filter=lfs diff=lfs merge=lfs -text
|
| 16 |
+
*.pth filter=lfs diff=lfs merge=lfs -text
|
models/MiniLM-L6-H384-uncased/README.md
ADDED
|
@@ -0,0 +1,7 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
---
|
| 2 |
+
license: mit
|
| 3 |
+
---
|
| 4 |
+
|
| 5 |
+
## MiniLM: 6 Layer Version
|
| 6 |
+
|
| 7 |
+
This is a 6 layer version of [microsoft/MiniLM-L12-H384-uncased](https://huggingface.co/microsoft/MiniLM-L12-H384-uncased/) by keeping only every second layer.
|
models/MiniLM-L6-H384-uncased/config.json
ADDED
|
@@ -0,0 +1,24 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"_name_or_path": "microsoft/MiniLM-L12-H384-uncased",
|
| 3 |
+
"architectures": [
|
| 4 |
+
"BertModel"
|
| 5 |
+
],
|
| 6 |
+
"attention_probs_dropout_prob": 0.1,
|
| 7 |
+
"gradient_checkpointing": false,
|
| 8 |
+
"hidden_act": "gelu",
|
| 9 |
+
"hidden_dropout_prob": 0.1,
|
| 10 |
+
"hidden_size": 384,
|
| 11 |
+
"initializer_range": 0.02,
|
| 12 |
+
"intermediate_size": 1536,
|
| 13 |
+
"layer_norm_eps": 1e-12,
|
| 14 |
+
"max_position_embeddings": 512,
|
| 15 |
+
"model_type": "bert",
|
| 16 |
+
"num_attention_heads": 12,
|
| 17 |
+
"num_hidden_layers": 6,
|
| 18 |
+
"pad_token_id": 0,
|
| 19 |
+
"position_embedding_type": "absolute",
|
| 20 |
+
"transformers_version": "4.4.2",
|
| 21 |
+
"type_vocab_size": 2,
|
| 22 |
+
"use_cache": true,
|
| 23 |
+
"vocab_size": 30522
|
| 24 |
+
}
|
models/MiniLM-L6-H384-uncased/flax_model.msgpack
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:cc64ec084e314b03470e11b4c5170bb9a64db946dc738768251ce188933dbab8
|
| 3 |
+
size 90856603
|
models/MiniLM-L6-H384-uncased/pytorch_model.bin
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:ab5048f3effe06bccb318ee923df90cba4e918b309a0ac6b00c654ede0768b87
|
| 3 |
+
size 90898263
|
models/MiniLM-L6-H384-uncased/special_tokens_map.json
ADDED
|
@@ -0,0 +1 @@
|
|
|
|
|
|
|
| 1 |
+
{"unk_token": "[UNK]", "sep_token": "[SEP]", "pad_token": "[PAD]", "cls_token": "[CLS]", "mask_token": "[MASK]"}
|
models/MiniLM-L6-H384-uncased/tokenizer_config.json
ADDED
|
@@ -0,0 +1 @@
|
|
|
|
|
|
|
| 1 |
+
{"do_lower_case": true, "unk_token": "[UNK]", "sep_token": "[SEP]", "pad_token": "[PAD]", "cls_token": "[CLS]", "mask_token": "[MASK]", "tokenize_chinese_chars": true, "strip_accents": null, "name_or_path": "microsoft/MiniLM-L12-H384-uncased", "do_basic_tokenize": true, "never_split": null, "model_max_length": 512}
|
models/MiniLM-L6-H384-uncased/vocab.txt
ADDED
|
The diff for this file is too large to render.
See raw diff
|
|
|
models/Qwen3-4B-Instruct-2507/.gitattributes
ADDED
|
@@ -0,0 +1,36 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
*.7z filter=lfs diff=lfs merge=lfs -text
|
| 2 |
+
*.arrow filter=lfs diff=lfs merge=lfs -text
|
| 3 |
+
*.bin filter=lfs diff=lfs merge=lfs -text
|
| 4 |
+
*.bz2 filter=lfs diff=lfs merge=lfs -text
|
| 5 |
+
*.ckpt filter=lfs diff=lfs merge=lfs -text
|
| 6 |
+
*.ftz filter=lfs diff=lfs merge=lfs -text
|
| 7 |
+
*.gz filter=lfs diff=lfs merge=lfs -text
|
| 8 |
+
*.h5 filter=lfs diff=lfs merge=lfs -text
|
| 9 |
+
*.joblib filter=lfs diff=lfs merge=lfs -text
|
| 10 |
+
*.lfs.* filter=lfs diff=lfs merge=lfs -text
|
| 11 |
+
*.mlmodel filter=lfs diff=lfs merge=lfs -text
|
| 12 |
+
*.model filter=lfs diff=lfs merge=lfs -text
|
| 13 |
+
*.msgpack filter=lfs diff=lfs merge=lfs -text
|
| 14 |
+
*.npy filter=lfs diff=lfs merge=lfs -text
|
| 15 |
+
*.npz filter=lfs diff=lfs merge=lfs -text
|
| 16 |
+
*.onnx filter=lfs diff=lfs merge=lfs -text
|
| 17 |
+
*.ot filter=lfs diff=lfs merge=lfs -text
|
| 18 |
+
*.parquet filter=lfs diff=lfs merge=lfs -text
|
| 19 |
+
*.pb filter=lfs diff=lfs merge=lfs -text
|
| 20 |
+
*.pickle filter=lfs diff=lfs merge=lfs -text
|
| 21 |
+
*.pkl filter=lfs diff=lfs merge=lfs -text
|
| 22 |
+
*.pt filter=lfs diff=lfs merge=lfs -text
|
| 23 |
+
*.pth filter=lfs diff=lfs merge=lfs -text
|
| 24 |
+
*.rar filter=lfs diff=lfs merge=lfs -text
|
| 25 |
+
*.safetensors filter=lfs diff=lfs merge=lfs -text
|
| 26 |
+
saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
| 27 |
+
*.tar.* filter=lfs diff=lfs merge=lfs -text
|
| 28 |
+
*.tar filter=lfs diff=lfs merge=lfs -text
|
| 29 |
+
*.tflite filter=lfs diff=lfs merge=lfs -text
|
| 30 |
+
*.tgz filter=lfs diff=lfs merge=lfs -text
|
| 31 |
+
*.wasm filter=lfs diff=lfs merge=lfs -text
|
| 32 |
+
*.xz filter=lfs diff=lfs merge=lfs -text
|
| 33 |
+
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 34 |
+
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
+
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
| 36 |
+
tokenizer.json filter=lfs diff=lfs merge=lfs -text
|
models/Qwen3-4B-Instruct-2507/LICENSE
ADDED
|
@@ -0,0 +1,202 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
|
| 2 |
+
Apache License
|
| 3 |
+
Version 2.0, January 2004
|
| 4 |
+
http://www.apache.org/licenses/
|
| 5 |
+
|
| 6 |
+
TERMS AND CONDITIONS FOR USE, REPRODUCTION, AND DISTRIBUTION
|
| 7 |
+
|
| 8 |
+
1. Definitions.
|
| 9 |
+
|
| 10 |
+
"License" shall mean the terms and conditions for use, reproduction,
|
| 11 |
+
and distribution as defined by Sections 1 through 9 of this document.
|
| 12 |
+
|
| 13 |
+
"Licensor" shall mean the copyright owner or entity authorized by
|
| 14 |
+
the copyright owner that is granting the License.
|
| 15 |
+
|
| 16 |
+
"Legal Entity" shall mean the union of the acting entity and all
|
| 17 |
+
other entities that control, are controlled by, or are under common
|
| 18 |
+
control with that entity. For the purposes of this definition,
|
| 19 |
+
"control" means (i) the power, direct or indirect, to cause the
|
| 20 |
+
direction or management of such entity, whether by contract or
|
| 21 |
+
otherwise, or (ii) ownership of fifty percent (50%) or more of the
|
| 22 |
+
outstanding shares, or (iii) beneficial ownership of such entity.
|
| 23 |
+
|
| 24 |
+
"You" (or "Your") shall mean an individual or Legal Entity
|
| 25 |
+
exercising permissions granted by this License.
|
| 26 |
+
|
| 27 |
+
"Source" form shall mean the preferred form for making modifications,
|
| 28 |
+
including but not limited to software source code, documentation
|
| 29 |
+
source, and configuration files.
|
| 30 |
+
|
| 31 |
+
"Object" form shall mean any form resulting from mechanical
|
| 32 |
+
transformation or translation of a Source form, including but
|
| 33 |
+
not limited to compiled object code, generated documentation,
|
| 34 |
+
and conversions to other media types.
|
| 35 |
+
|
| 36 |
+
"Work" shall mean the work of authorship, whether in Source or
|
| 37 |
+
Object form, made available under the License, as indicated by a
|
| 38 |
+
copyright notice that is included in or attached to the work
|
| 39 |
+
(an example is provided in the Appendix below).
|
| 40 |
+
|
| 41 |
+
"Derivative Works" shall mean any work, whether in Source or Object
|
| 42 |
+
form, that is based on (or derived from) the Work and for which the
|
| 43 |
+
editorial revisions, annotations, elaborations, or other modifications
|
| 44 |
+
represent, as a whole, an original work of authorship. For the purposes
|
| 45 |
+
of this License, Derivative Works shall not include works that remain
|
| 46 |
+
separable from, or merely link (or bind by name) to the interfaces of,
|
| 47 |
+
the Work and Derivative Works thereof.
|
| 48 |
+
|
| 49 |
+
"Contribution" shall mean any work of authorship, including
|
| 50 |
+
the original version of the Work and any modifications or additions
|
| 51 |
+
to that Work or Derivative Works thereof, that is intentionally
|
| 52 |
+
submitted to Licensor for inclusion in the Work by the copyright owner
|
| 53 |
+
or by an individual or Legal Entity authorized to submit on behalf of
|
| 54 |
+
the copyright owner. For the purposes of this definition, "submitted"
|
| 55 |
+
means any form of electronic, verbal, or written communication sent
|
| 56 |
+
to the Licensor or its representatives, including but not limited to
|
| 57 |
+
communication on electronic mailing lists, source code control systems,
|
| 58 |
+
and issue tracking systems that are managed by, or on behalf of, the
|
| 59 |
+
Licensor for the purpose of discussing and improving the Work, but
|
| 60 |
+
excluding communication that is conspicuously marked or otherwise
|
| 61 |
+
designated in writing by the copyright owner as "Not a Contribution."
|
| 62 |
+
|
| 63 |
+
"Contributor" shall mean Licensor and any individual or Legal Entity
|
| 64 |
+
on behalf of whom a Contribution has been received by Licensor and
|
| 65 |
+
subsequently incorporated within the Work.
|
| 66 |
+
|
| 67 |
+
2. Grant of Copyright License. Subject to the terms and conditions of
|
| 68 |
+
this License, each Contributor hereby grants to You a perpetual,
|
| 69 |
+
worldwide, non-exclusive, no-charge, royalty-free, irrevocable
|
| 70 |
+
copyright license to reproduce, prepare Derivative Works of,
|
| 71 |
+
publicly display, publicly perform, sublicense, and distribute the
|
| 72 |
+
Work and such Derivative Works in Source or Object form.
|
| 73 |
+
|
| 74 |
+
3. Grant of Patent License. Subject to the terms and conditions of
|
| 75 |
+
this License, each Contributor hereby grants to You a perpetual,
|
| 76 |
+
worldwide, non-exclusive, no-charge, royalty-free, irrevocable
|
| 77 |
+
(except as stated in this section) patent license to make, have made,
|
| 78 |
+
use, offer to sell, sell, import, and otherwise transfer the Work,
|
| 79 |
+
where such license applies only to those patent claims licensable
|
| 80 |
+
by such Contributor that are necessarily infringed by their
|
| 81 |
+
Contribution(s) alone or by combination of their Contribution(s)
|
| 82 |
+
with the Work to which such Contribution(s) was submitted. If You
|
| 83 |
+
institute patent litigation against any entity (including a
|
| 84 |
+
cross-claim or counterclaim in a lawsuit) alleging that the Work
|
| 85 |
+
or a Contribution incorporated within the Work constitutes direct
|
| 86 |
+
or contributory patent infringement, then any patent licenses
|
| 87 |
+
granted to You under this License for that Work shall terminate
|
| 88 |
+
as of the date such litigation is filed.
|
| 89 |
+
|
| 90 |
+
4. Redistribution. You may reproduce and distribute copies of the
|
| 91 |
+
Work or Derivative Works thereof in any medium, with or without
|
| 92 |
+
modifications, and in Source or Object form, provided that You
|
| 93 |
+
meet the following conditions:
|
| 94 |
+
|
| 95 |
+
(a) You must give any other recipients of the Work or
|
| 96 |
+
Derivative Works a copy of this License; and
|
| 97 |
+
|
| 98 |
+
(b) You must cause any modified files to carry prominent notices
|
| 99 |
+
stating that You changed the files; and
|
| 100 |
+
|
| 101 |
+
(c) You must retain, in the Source form of any Derivative Works
|
| 102 |
+
that You distribute, all copyright, patent, trademark, and
|
| 103 |
+
attribution notices from the Source form of the Work,
|
| 104 |
+
excluding those notices that do not pertain to any part of
|
| 105 |
+
the Derivative Works; and
|
| 106 |
+
|
| 107 |
+
(d) If the Work includes a "NOTICE" text file as part of its
|
| 108 |
+
distribution, then any Derivative Works that You distribute must
|
| 109 |
+
include a readable copy of the attribution notices contained
|
| 110 |
+
within such NOTICE file, excluding those notices that do not
|
| 111 |
+
pertain to any part of the Derivative Works, in at least one
|
| 112 |
+
of the following places: within a NOTICE text file distributed
|
| 113 |
+
as part of the Derivative Works; within the Source form or
|
| 114 |
+
documentation, if provided along with the Derivative Works; or,
|
| 115 |
+
within a display generated by the Derivative Works, if and
|
| 116 |
+
wherever such third-party notices normally appear. The contents
|
| 117 |
+
of the NOTICE file are for informational purposes only and
|
| 118 |
+
do not modify the License. You may add Your own attribution
|
| 119 |
+
notices within Derivative Works that You distribute, alongside
|
| 120 |
+
or as an addendum to the NOTICE text from the Work, provided
|
| 121 |
+
that such additional attribution notices cannot be construed
|
| 122 |
+
as modifying the License.
|
| 123 |
+
|
| 124 |
+
You may add Your own copyright statement to Your modifications and
|
| 125 |
+
may provide additional or different license terms and conditions
|
| 126 |
+
for use, reproduction, or distribution of Your modifications, or
|
| 127 |
+
for any such Derivative Works as a whole, provided Your use,
|
| 128 |
+
reproduction, and distribution of the Work otherwise complies with
|
| 129 |
+
the conditions stated in this License.
|
| 130 |
+
|
| 131 |
+
5. Submission of Contributions. Unless You explicitly state otherwise,
|
| 132 |
+
any Contribution intentionally submitted for inclusion in the Work
|
| 133 |
+
by You to the Licensor shall be under the terms and conditions of
|
| 134 |
+
this License, without any additional terms or conditions.
|
| 135 |
+
Notwithstanding the above, nothing herein shall supersede or modify
|
| 136 |
+
the terms of any separate license agreement you may have executed
|
| 137 |
+
with Licensor regarding such Contributions.
|
| 138 |
+
|
| 139 |
+
6. Trademarks. This License does not grant permission to use the trade
|
| 140 |
+
names, trademarks, service marks, or product names of the Licensor,
|
| 141 |
+
except as required for reasonable and customary use in describing the
|
| 142 |
+
origin of the Work and reproducing the content of the NOTICE file.
|
| 143 |
+
|
| 144 |
+
7. Disclaimer of Warranty. Unless required by applicable law or
|
| 145 |
+
agreed to in writing, Licensor provides the Work (and each
|
| 146 |
+
Contributor provides its Contributions) on an "AS IS" BASIS,
|
| 147 |
+
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or
|
| 148 |
+
implied, including, without limitation, any warranties or conditions
|
| 149 |
+
of TITLE, NON-INFRINGEMENT, MERCHANTABILITY, or FITNESS FOR A
|
| 150 |
+
PARTICULAR PURPOSE. You are solely responsible for determining the
|
| 151 |
+
appropriateness of using or redistributing the Work and assume any
|
| 152 |
+
risks associated with Your exercise of permissions under this License.
|
| 153 |
+
|
| 154 |
+
8. Limitation of Liability. In no event and under no legal theory,
|
| 155 |
+
whether in tort (including negligence), contract, or otherwise,
|
| 156 |
+
unless required by applicable law (such as deliberate and grossly
|
| 157 |
+
negligent acts) or agreed to in writing, shall any Contributor be
|
| 158 |
+
liable to You for damages, including any direct, indirect, special,
|
| 159 |
+
incidental, or consequential damages of any character arising as a
|
| 160 |
+
result of this License or out of the use or inability to use the
|
| 161 |
+
Work (including but not limited to damages for loss of goodwill,
|
| 162 |
+
work stoppage, computer failure or malfunction, or any and all
|
| 163 |
+
other commercial damages or losses), even if such Contributor
|
| 164 |
+
has been advised of the possibility of such damages.
|
| 165 |
+
|
| 166 |
+
9. Accepting Warranty or Additional Liability. While redistributing
|
| 167 |
+
the Work or Derivative Works thereof, You may choose to offer,
|
| 168 |
+
and charge a fee for, acceptance of support, warranty, indemnity,
|
| 169 |
+
or other liability obligations and/or rights consistent with this
|
| 170 |
+
License. However, in accepting such obligations, You may act only
|
| 171 |
+
on Your own behalf and on Your sole responsibility, not on behalf
|
| 172 |
+
of any other Contributor, and only if You agree to indemnify,
|
| 173 |
+
defend, and hold each Contributor harmless for any liability
|
| 174 |
+
incurred by, or claims asserted against, such Contributor by reason
|
| 175 |
+
of your accepting any such warranty or additional liability.
|
| 176 |
+
|
| 177 |
+
END OF TERMS AND CONDITIONS
|
| 178 |
+
|
| 179 |
+
APPENDIX: How to apply the Apache License to your work.
|
| 180 |
+
|
| 181 |
+
To apply the Apache License to your work, attach the following
|
| 182 |
+
boilerplate notice, with the fields enclosed by brackets "[]"
|
| 183 |
+
replaced with your own identifying information. (Don't include
|
| 184 |
+
the brackets!) The text should be enclosed in the appropriate
|
| 185 |
+
comment syntax for the file format. We also recommend that a
|
| 186 |
+
file or class name and description of purpose be included on the
|
| 187 |
+
same "printed page" as the copyright notice for easier
|
| 188 |
+
identification within third-party archives.
|
| 189 |
+
|
| 190 |
+
Copyright 2024 Alibaba Cloud
|
| 191 |
+
|
| 192 |
+
Licensed under the Apache License, Version 2.0 (the "License");
|
| 193 |
+
you may not use this file except in compliance with the License.
|
| 194 |
+
You may obtain a copy of the License at
|
| 195 |
+
|
| 196 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 197 |
+
|
| 198 |
+
Unless required by applicable law or agreed to in writing, software
|
| 199 |
+
distributed under the License is distributed on an "AS IS" BASIS,
|
| 200 |
+
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
| 201 |
+
See the License for the specific language governing permissions and
|
| 202 |
+
limitations under the License.
|
models/Qwen3-4B-Instruct-2507/README.md
ADDED
|
@@ -0,0 +1,211 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
---
|
| 2 |
+
library_name: transformers
|
| 3 |
+
license: apache-2.0
|
| 4 |
+
license_link: https://huggingface.co/Qwen/Qwen3-4B-Instruct-2507/blob/main/LICENSE
|
| 5 |
+
pipeline_tag: text-generation
|
| 6 |
+
---
|
| 7 |
+
|
| 8 |
+
# Qwen3-4B-Instruct-2507
|
| 9 |
+
<a href="https://chat.qwen.ai" target="_blank" style="margin: 2px;">
|
| 10 |
+
<img alt="Chat" src="https://img.shields.io/badge/%F0%9F%92%9C%EF%B8%8F%20Qwen%20Chat%20-536af5" style="display: inline-block; vertical-align: middle;"/>
|
| 11 |
+
</a>
|
| 12 |
+
|
| 13 |
+
## Highlights
|
| 14 |
+
|
| 15 |
+
We introduce the updated version of the **Qwen3-4B non-thinking mode**, named **Qwen3-4B-Instruct-2507**, featuring the following key enhancements:
|
| 16 |
+
|
| 17 |
+
- **Significant improvements** in general capabilities, including **instruction following, logical reasoning, text comprehension, mathematics, science, coding and tool usage**.
|
| 18 |
+
- **Substantial gains** in long-tail knowledge coverage across **multiple languages**.
|
| 19 |
+
- **Markedly better alignment** with user preferences in **subjective and open-ended tasks**, enabling more helpful responses and higher-quality text generation.
|
| 20 |
+
- **Enhanced capabilities** in **256K long-context understanding**.
|
| 21 |
+
|
| 22 |
+
|
| 23 |
+
|
| 24 |
+
## Model Overview
|
| 25 |
+
|
| 26 |
+
**Qwen3-4B-Instruct-2507** has the following features:
|
| 27 |
+
- Type: Causal Language Models
|
| 28 |
+
- Training Stage: Pretraining & Post-training
|
| 29 |
+
- Number of Parameters: 4.0B
|
| 30 |
+
- Number of Paramaters (Non-Embedding): 3.6B
|
| 31 |
+
- Number of Layers: 36
|
| 32 |
+
- Number of Attention Heads (GQA): 32 for Q and 8 for KV
|
| 33 |
+
- Context Length: **262,144 natively**.
|
| 34 |
+
|
| 35 |
+
**NOTE: This model supports only non-thinking mode and does not generate ``<think></think>`` blocks in its output. Meanwhile, specifying `enable_thinking=False` is no longer required.**
|
| 36 |
+
|
| 37 |
+
For more details, including benchmark evaluation, hardware requirements, and inference performance, please refer to our [blog](https://qwenlm.github.io/blog/qwen3/), [GitHub](https://github.com/QwenLM/Qwen3), and [Documentation](https://qwen.readthedocs.io/en/latest/).
|
| 38 |
+
|
| 39 |
+
|
| 40 |
+
## Performance
|
| 41 |
+
|
| 42 |
+
| | GPT-4.1-nano-2025-04-14 | Qwen3-30B-A3B Non-Thinking | Qwen3-4B Non-Thinking | Qwen3-4B-Instruct-2507 |
|
| 43 |
+
|--- | --- | --- | --- | --- |
|
| 44 |
+
| **Knowledge** | | | |
|
| 45 |
+
| MMLU-Pro | 62.8 | 69.1 | 58.0 | **69.6** |
|
| 46 |
+
| MMLU-Redux | 80.2 | 84.1 | 77.3 | **84.2** |
|
| 47 |
+
| GPQA | 50.3 | 54.8 | 41.7 | **62.0** |
|
| 48 |
+
| SuperGPQA | 32.2 | 42.2 | 32.0 | **42.8** |
|
| 49 |
+
| **Reasoning** | | | |
|
| 50 |
+
| AIME25 | 22.7 | 21.6 | 19.1 | **47.4** |
|
| 51 |
+
| HMMT25 | 9.7 | 12.0 | 12.1 | **31.0** |
|
| 52 |
+
| ZebraLogic | 14.8 | 33.2 | 35.2 | **80.2** |
|
| 53 |
+
| LiveBench 20241125 | 41.5 | 59.4 | 48.4 | **63.0** |
|
| 54 |
+
| **Coding** | | | |
|
| 55 |
+
| LiveCodeBench v6 (25.02-25.05) | 31.5 | 29.0 | 26.4 | **35.1** |
|
| 56 |
+
| MultiPL-E | 76.3 | 74.6 | 66.6 | **76.8** |
|
| 57 |
+
| Aider-Polyglot | 9.8 | **24.4** | 13.8 | 12.9 |
|
| 58 |
+
| **Alignment** | | | |
|
| 59 |
+
| IFEval | 74.5 | **83.7** | 81.2 | 83.4 |
|
| 60 |
+
| Arena-Hard v2* | 15.9 | 24.8 | 9.5 | **43.4** |
|
| 61 |
+
| Creative Writing v3 | 72.7 | 68.1 | 53.6 | **83.5** |
|
| 62 |
+
| WritingBench | 66.9 | 72.2 | 68.5 | **83.4** |
|
| 63 |
+
| **Agent** | | | |
|
| 64 |
+
| BFCL-v3 | 53.0 | 58.6 | 57.6 | **61.9** |
|
| 65 |
+
| TAU1-Retail | 23.5 | 38.3 | 24.3 | **48.7** |
|
| 66 |
+
| TAU1-Airline | 14.0 | 18.0 | 16.0 | **32.0** |
|
| 67 |
+
| TAU2-Retail | - | 31.6 | 28.1 | **40.4** |
|
| 68 |
+
| TAU2-Airline | - | 18.0 | 12.0 | **24.0** |
|
| 69 |
+
| TAU2-Telecom | - | **18.4** | 17.5 | 13.2 |
|
| 70 |
+
| **Multilingualism** | | | |
|
| 71 |
+
| MultiIF | 60.7 | **70.8** | 61.3 | 69.0 |
|
| 72 |
+
| MMLU-ProX | 56.2 | **65.1** | 49.6 | 61.6 |
|
| 73 |
+
| INCLUDE | 58.6 | **67.8** | 53.8 | 60.1 |
|
| 74 |
+
| PolyMATH | 15.6 | 23.3 | 16.6 | **31.1** |
|
| 75 |
+
|
| 76 |
+
*: For reproducibility, we report the win rates evaluated by GPT-4.1.
|
| 77 |
+
|
| 78 |
+
|
| 79 |
+
## Quickstart
|
| 80 |
+
|
| 81 |
+
The code of Qwen3 has been in the latest Hugging Face `transformers` and we advise you to use the latest version of `transformers`.
|
| 82 |
+
|
| 83 |
+
With `transformers<4.51.0`, you will encounter the following error:
|
| 84 |
+
```
|
| 85 |
+
KeyError: 'qwen3'
|
| 86 |
+
```
|
| 87 |
+
|
| 88 |
+
The following contains a code snippet illustrating how to use the model generate content based on given inputs.
|
| 89 |
+
```python
|
| 90 |
+
from transformers import AutoModelForCausalLM, AutoTokenizer
|
| 91 |
+
|
| 92 |
+
model_name = "Qwen/Qwen3-4B-Instruct-2507"
|
| 93 |
+
|
| 94 |
+
# load the tokenizer and the model
|
| 95 |
+
tokenizer = AutoTokenizer.from_pretrained(model_name)
|
| 96 |
+
model = AutoModelForCausalLM.from_pretrained(
|
| 97 |
+
model_name,
|
| 98 |
+
torch_dtype="auto",
|
| 99 |
+
device_map="auto"
|
| 100 |
+
)
|
| 101 |
+
|
| 102 |
+
# prepare the model input
|
| 103 |
+
prompt = "Give me a short introduction to large language model."
|
| 104 |
+
messages = [
|
| 105 |
+
{"role": "user", "content": prompt}
|
| 106 |
+
]
|
| 107 |
+
text = tokenizer.apply_chat_template(
|
| 108 |
+
messages,
|
| 109 |
+
tokenize=False,
|
| 110 |
+
add_generation_prompt=True,
|
| 111 |
+
)
|
| 112 |
+
model_inputs = tokenizer([text], return_tensors="pt").to(model.device)
|
| 113 |
+
|
| 114 |
+
# conduct text completion
|
| 115 |
+
generated_ids = model.generate(
|
| 116 |
+
**model_inputs,
|
| 117 |
+
max_new_tokens=16384
|
| 118 |
+
)
|
| 119 |
+
output_ids = generated_ids[0][len(model_inputs.input_ids[0]):].tolist()
|
| 120 |
+
|
| 121 |
+
content = tokenizer.decode(output_ids, skip_special_tokens=True)
|
| 122 |
+
|
| 123 |
+
print("content:", content)
|
| 124 |
+
```
|
| 125 |
+
|
| 126 |
+
For deployment, you can use `sglang>=0.4.6.post1` or `vllm>=0.8.5` or to create an OpenAI-compatible API endpoint:
|
| 127 |
+
- SGLang:
|
| 128 |
+
```shell
|
| 129 |
+
python -m sglang.launch_server --model-path Qwen/Qwen3-4B-Instruct-2507 --context-length 262144
|
| 130 |
+
```
|
| 131 |
+
- vLLM:
|
| 132 |
+
```shell
|
| 133 |
+
vllm serve Qwen/Qwen3-4B-Instruct-2507 --max-model-len 262144
|
| 134 |
+
```
|
| 135 |
+
|
| 136 |
+
**Note: If you encounter out-of-memory (OOM) issues, consider reducing the context length to a shorter value, such as `32,768`.**
|
| 137 |
+
|
| 138 |
+
For local use, applications such as Ollama, LMStudio, MLX-LM, llama.cpp, and KTransformers have also supported Qwen3.
|
| 139 |
+
|
| 140 |
+
## Agentic Use
|
| 141 |
+
|
| 142 |
+
Qwen3 excels in tool calling capabilities. We recommend using [Qwen-Agent](https://github.com/QwenLM/Qwen-Agent) to make the best use of agentic ability of Qwen3. Qwen-Agent encapsulates tool-calling templates and tool-calling parsers internally, greatly reducing coding complexity.
|
| 143 |
+
|
| 144 |
+
To define the available tools, you can use the MCP configuration file, use the integrated tool of Qwen-Agent, or integrate other tools by yourself.
|
| 145 |
+
```python
|
| 146 |
+
from qwen_agent.agents import Assistant
|
| 147 |
+
|
| 148 |
+
# Define LLM
|
| 149 |
+
llm_cfg = {
|
| 150 |
+
'model': 'Qwen3-4B-Instruct-2507',
|
| 151 |
+
|
| 152 |
+
# Use a custom endpoint compatible with OpenAI API:
|
| 153 |
+
'model_server': 'http://localhost:8000/v1', # api_base
|
| 154 |
+
'api_key': 'EMPTY',
|
| 155 |
+
}
|
| 156 |
+
|
| 157 |
+
# Define Tools
|
| 158 |
+
tools = [
|
| 159 |
+
{'mcpServers': { # You can specify the MCP configuration file
|
| 160 |
+
'time': {
|
| 161 |
+
'command': 'uvx',
|
| 162 |
+
'args': ['mcp-server-time', '--local-timezone=Asia/Shanghai']
|
| 163 |
+
},
|
| 164 |
+
"fetch": {
|
| 165 |
+
"command": "uvx",
|
| 166 |
+
"args": ["mcp-server-fetch"]
|
| 167 |
+
}
|
| 168 |
+
}
|
| 169 |
+
},
|
| 170 |
+
'code_interpreter', # Built-in tools
|
| 171 |
+
]
|
| 172 |
+
|
| 173 |
+
# Define Agent
|
| 174 |
+
bot = Assistant(llm=llm_cfg, function_list=tools)
|
| 175 |
+
|
| 176 |
+
# Streaming generation
|
| 177 |
+
messages = [{'role': 'user', 'content': 'https://qwenlm.github.io/blog/ Introduce the latest developments of Qwen'}]
|
| 178 |
+
for responses in bot.run(messages=messages):
|
| 179 |
+
pass
|
| 180 |
+
print(responses)
|
| 181 |
+
```
|
| 182 |
+
|
| 183 |
+
## Best Practices
|
| 184 |
+
|
| 185 |
+
To achieve optimal performance, we recommend the following settings:
|
| 186 |
+
|
| 187 |
+
1. **Sampling Parameters**:
|
| 188 |
+
- We suggest using `Temperature=0.7`, `TopP=0.8`, `TopK=20`, and `MinP=0`.
|
| 189 |
+
- For supported frameworks, you can adjust the `presence_penalty` parameter between 0 and 2 to reduce endless repetitions. However, using a higher value may occasionally result in language mixing and a slight decrease in model performance.
|
| 190 |
+
|
| 191 |
+
2. **Adequate Output Length**: We recommend using an output length of 16,384 tokens for most queries, which is adequate for instruct models.
|
| 192 |
+
|
| 193 |
+
3. **Standardize Output Format**: We recommend using prompts to standardize model outputs when benchmarking.
|
| 194 |
+
- **Math Problems**: Include "Please reason step by step, and put your final answer within \boxed{}." in the prompt.
|
| 195 |
+
- **Multiple-Choice Questions**: Add the following JSON structure to the prompt to standardize responses: "Please show your choice in the `answer` field with only the choice letter, e.g., `"answer": "C"`."
|
| 196 |
+
|
| 197 |
+
### Citation
|
| 198 |
+
|
| 199 |
+
If you find our work helpful, feel free to give us a cite.
|
| 200 |
+
|
| 201 |
+
```
|
| 202 |
+
@misc{qwen3technicalreport,
|
| 203 |
+
title={Qwen3 Technical Report},
|
| 204 |
+
author={Qwen Team},
|
| 205 |
+
year={2025},
|
| 206 |
+
eprint={2505.09388},
|
| 207 |
+
archivePrefix={arXiv},
|
| 208 |
+
primaryClass={cs.CL},
|
| 209 |
+
url={https://arxiv.org/abs/2505.09388},
|
| 210 |
+
}
|
| 211 |
+
```
|
models/Qwen3-4B-Instruct-2507/config.json
ADDED
|
@@ -0,0 +1,30 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"architectures": [
|
| 3 |
+
"Qwen3ForCausalLM"
|
| 4 |
+
],
|
| 5 |
+
"attention_bias": false,
|
| 6 |
+
"attention_dropout": 0.0,
|
| 7 |
+
"bos_token_id": 151643,
|
| 8 |
+
"eos_token_id": 151645,
|
| 9 |
+
"head_dim": 128,
|
| 10 |
+
"hidden_act": "silu",
|
| 11 |
+
"hidden_size": 2560,
|
| 12 |
+
"initializer_range": 0.02,
|
| 13 |
+
"intermediate_size": 9728,
|
| 14 |
+
"max_position_embeddings": 262144,
|
| 15 |
+
"max_window_layers": 36,
|
| 16 |
+
"model_type": "qwen3",
|
| 17 |
+
"num_attention_heads": 32,
|
| 18 |
+
"num_hidden_layers": 36,
|
| 19 |
+
"num_key_value_heads": 8,
|
| 20 |
+
"rms_norm_eps": 1e-06,
|
| 21 |
+
"rope_scaling": null,
|
| 22 |
+
"rope_theta": 5000000,
|
| 23 |
+
"sliding_window": null,
|
| 24 |
+
"tie_word_embeddings": true,
|
| 25 |
+
"torch_dtype": "bfloat16",
|
| 26 |
+
"transformers_version": "4.51.0",
|
| 27 |
+
"use_cache": true,
|
| 28 |
+
"use_sliding_window": false,
|
| 29 |
+
"vocab_size": 151936
|
| 30 |
+
}
|
models/Qwen3-4B-Instruct-2507/generation_config.json
ADDED
|
@@ -0,0 +1,13 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"bos_token_id": 151643,
|
| 3 |
+
"do_sample": true,
|
| 4 |
+
"eos_token_id": [
|
| 5 |
+
151645,
|
| 6 |
+
151643
|
| 7 |
+
],
|
| 8 |
+
"pad_token_id": 151643,
|
| 9 |
+
"temperature": 0.7,
|
| 10 |
+
"top_k": 20,
|
| 11 |
+
"top_p": 0.8,
|
| 12 |
+
"transformers_version": "4.51.0"
|
| 13 |
+
}
|
models/Qwen3-4B-Instruct-2507/merges.txt
ADDED
|
The diff for this file is too large to render.
See raw diff
|
|
|
models/Qwen3-4B-Instruct-2507/model-00001-of-00003.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:75311d91bb08cf0b882913da464a1e722a31fb44db35208663487efb7a3d8ed6
|
| 3 |
+
size 3957900840
|
models/Qwen3-4B-Instruct-2507/model-00002-of-00003.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:0b48adbb1f60e901153d91907ba11ce63bd4b8b584482e730f48808d055dfba1
|
| 3 |
+
size 3987450520
|
models/Qwen3-4B-Instruct-2507/model-00003-of-00003.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:7dd39ccca5e4de123c74c14af44c9bf2eb75df33b4614382af0134528e060d5d
|
| 3 |
+
size 99630640
|
models/Qwen3-4B-Instruct-2507/model.safetensors.index.json
ADDED
|
@@ -0,0 +1,405 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"metadata": {
|
| 3 |
+
"total_size": 8045591552
|
| 4 |
+
},
|
| 5 |
+
"weight_map": {
|
| 6 |
+
"model.embed_tokens.weight": "model-00001-of-00003.safetensors",
|
| 7 |
+
"model.layers.0.input_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 8 |
+
"model.layers.0.mlp.down_proj.weight": "model-00001-of-00003.safetensors",
|
| 9 |
+
"model.layers.0.mlp.gate_proj.weight": "model-00001-of-00003.safetensors",
|
| 10 |
+
"model.layers.0.mlp.up_proj.weight": "model-00001-of-00003.safetensors",
|
| 11 |
+
"model.layers.0.post_attention_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 12 |
+
"model.layers.0.self_attn.k_norm.weight": "model-00001-of-00003.safetensors",
|
| 13 |
+
"model.layers.0.self_attn.k_proj.weight": "model-00001-of-00003.safetensors",
|
| 14 |
+
"model.layers.0.self_attn.o_proj.weight": "model-00001-of-00003.safetensors",
|
| 15 |
+
"model.layers.0.self_attn.q_norm.weight": "model-00001-of-00003.safetensors",
|
| 16 |
+
"model.layers.0.self_attn.q_proj.weight": "model-00001-of-00003.safetensors",
|
| 17 |
+
"model.layers.0.self_attn.v_proj.weight": "model-00001-of-00003.safetensors",
|
| 18 |
+
"model.layers.1.input_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 19 |
+
"model.layers.1.mlp.down_proj.weight": "model-00001-of-00003.safetensors",
|
| 20 |
+
"model.layers.1.mlp.gate_proj.weight": "model-00001-of-00003.safetensors",
|
| 21 |
+
"model.layers.1.mlp.up_proj.weight": "model-00001-of-00003.safetensors",
|
| 22 |
+
"model.layers.1.post_attention_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 23 |
+
"model.layers.1.self_attn.k_norm.weight": "model-00001-of-00003.safetensors",
|
| 24 |
+
"model.layers.1.self_attn.k_proj.weight": "model-00001-of-00003.safetensors",
|
| 25 |
+
"model.layers.1.self_attn.o_proj.weight": "model-00001-of-00003.safetensors",
|
| 26 |
+
"model.layers.1.self_attn.q_norm.weight": "model-00001-of-00003.safetensors",
|
| 27 |
+
"model.layers.1.self_attn.q_proj.weight": "model-00001-of-00003.safetensors",
|
| 28 |
+
"model.layers.1.self_attn.v_proj.weight": "model-00001-of-00003.safetensors",
|
| 29 |
+
"model.layers.10.input_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 30 |
+
"model.layers.10.mlp.down_proj.weight": "model-00001-of-00003.safetensors",
|
| 31 |
+
"model.layers.10.mlp.gate_proj.weight": "model-00001-of-00003.safetensors",
|
| 32 |
+
"model.layers.10.mlp.up_proj.weight": "model-00001-of-00003.safetensors",
|
| 33 |
+
"model.layers.10.post_attention_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 34 |
+
"model.layers.10.self_attn.k_norm.weight": "model-00001-of-00003.safetensors",
|
| 35 |
+
"model.layers.10.self_attn.k_proj.weight": "model-00001-of-00003.safetensors",
|
| 36 |
+
"model.layers.10.self_attn.o_proj.weight": "model-00001-of-00003.safetensors",
|
| 37 |
+
"model.layers.10.self_attn.q_norm.weight": "model-00001-of-00003.safetensors",
|
| 38 |
+
"model.layers.10.self_attn.q_proj.weight": "model-00001-of-00003.safetensors",
|
| 39 |
+
"model.layers.10.self_attn.v_proj.weight": "model-00001-of-00003.safetensors",
|
| 40 |
+
"model.layers.11.input_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 41 |
+
"model.layers.11.mlp.down_proj.weight": "model-00001-of-00003.safetensors",
|
| 42 |
+
"model.layers.11.mlp.gate_proj.weight": "model-00001-of-00003.safetensors",
|
| 43 |
+
"model.layers.11.mlp.up_proj.weight": "model-00001-of-00003.safetensors",
|
| 44 |
+
"model.layers.11.post_attention_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 45 |
+
"model.layers.11.self_attn.k_norm.weight": "model-00001-of-00003.safetensors",
|
| 46 |
+
"model.layers.11.self_attn.k_proj.weight": "model-00001-of-00003.safetensors",
|
| 47 |
+
"model.layers.11.self_attn.o_proj.weight": "model-00001-of-00003.safetensors",
|
| 48 |
+
"model.layers.11.self_attn.q_norm.weight": "model-00001-of-00003.safetensors",
|
| 49 |
+
"model.layers.11.self_attn.q_proj.weight": "model-00001-of-00003.safetensors",
|
| 50 |
+
"model.layers.11.self_attn.v_proj.weight": "model-00001-of-00003.safetensors",
|
| 51 |
+
"model.layers.12.input_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 52 |
+
"model.layers.12.mlp.down_proj.weight": "model-00001-of-00003.safetensors",
|
| 53 |
+
"model.layers.12.mlp.gate_proj.weight": "model-00001-of-00003.safetensors",
|
| 54 |
+
"model.layers.12.mlp.up_proj.weight": "model-00001-of-00003.safetensors",
|
| 55 |
+
"model.layers.12.post_attention_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 56 |
+
"model.layers.12.self_attn.k_norm.weight": "model-00001-of-00003.safetensors",
|
| 57 |
+
"model.layers.12.self_attn.k_proj.weight": "model-00001-of-00003.safetensors",
|
| 58 |
+
"model.layers.12.self_attn.o_proj.weight": "model-00001-of-00003.safetensors",
|
| 59 |
+
"model.layers.12.self_attn.q_norm.weight": "model-00001-of-00003.safetensors",
|
| 60 |
+
"model.layers.12.self_attn.q_proj.weight": "model-00001-of-00003.safetensors",
|
| 61 |
+
"model.layers.12.self_attn.v_proj.weight": "model-00001-of-00003.safetensors",
|
| 62 |
+
"model.layers.13.input_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 63 |
+
"model.layers.13.mlp.down_proj.weight": "model-00001-of-00003.safetensors",
|
| 64 |
+
"model.layers.13.mlp.gate_proj.weight": "model-00001-of-00003.safetensors",
|
| 65 |
+
"model.layers.13.mlp.up_proj.weight": "model-00001-of-00003.safetensors",
|
| 66 |
+
"model.layers.13.post_attention_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 67 |
+
"model.layers.13.self_attn.k_norm.weight": "model-00001-of-00003.safetensors",
|
| 68 |
+
"model.layers.13.self_attn.k_proj.weight": "model-00001-of-00003.safetensors",
|
| 69 |
+
"model.layers.13.self_attn.o_proj.weight": "model-00001-of-00003.safetensors",
|
| 70 |
+
"model.layers.13.self_attn.q_norm.weight": "model-00001-of-00003.safetensors",
|
| 71 |
+
"model.layers.13.self_attn.q_proj.weight": "model-00001-of-00003.safetensors",
|
| 72 |
+
"model.layers.13.self_attn.v_proj.weight": "model-00001-of-00003.safetensors",
|
| 73 |
+
"model.layers.14.input_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 74 |
+
"model.layers.14.mlp.down_proj.weight": "model-00001-of-00003.safetensors",
|
| 75 |
+
"model.layers.14.mlp.gate_proj.weight": "model-00001-of-00003.safetensors",
|
| 76 |
+
"model.layers.14.mlp.up_proj.weight": "model-00001-of-00003.safetensors",
|
| 77 |
+
"model.layers.14.post_attention_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 78 |
+
"model.layers.14.self_attn.k_norm.weight": "model-00001-of-00003.safetensors",
|
| 79 |
+
"model.layers.14.self_attn.k_proj.weight": "model-00001-of-00003.safetensors",
|
| 80 |
+
"model.layers.14.self_attn.o_proj.weight": "model-00001-of-00003.safetensors",
|
| 81 |
+
"model.layers.14.self_attn.q_norm.weight": "model-00001-of-00003.safetensors",
|
| 82 |
+
"model.layers.14.self_attn.q_proj.weight": "model-00001-of-00003.safetensors",
|
| 83 |
+
"model.layers.14.self_attn.v_proj.weight": "model-00001-of-00003.safetensors",
|
| 84 |
+
"model.layers.15.input_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 85 |
+
"model.layers.15.mlp.down_proj.weight": "model-00002-of-00003.safetensors",
|
| 86 |
+
"model.layers.15.mlp.gate_proj.weight": "model-00001-of-00003.safetensors",
|
| 87 |
+
"model.layers.15.mlp.up_proj.weight": "model-00001-of-00003.safetensors",
|
| 88 |
+
"model.layers.15.post_attention_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 89 |
+
"model.layers.15.self_attn.k_norm.weight": "model-00001-of-00003.safetensors",
|
| 90 |
+
"model.layers.15.self_attn.k_proj.weight": "model-00001-of-00003.safetensors",
|
| 91 |
+
"model.layers.15.self_attn.o_proj.weight": "model-00001-of-00003.safetensors",
|
| 92 |
+
"model.layers.15.self_attn.q_norm.weight": "model-00001-of-00003.safetensors",
|
| 93 |
+
"model.layers.15.self_attn.q_proj.weight": "model-00001-of-00003.safetensors",
|
| 94 |
+
"model.layers.15.self_attn.v_proj.weight": "model-00001-of-00003.safetensors",
|
| 95 |
+
"model.layers.16.input_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 96 |
+
"model.layers.16.mlp.down_proj.weight": "model-00002-of-00003.safetensors",
|
| 97 |
+
"model.layers.16.mlp.gate_proj.weight": "model-00002-of-00003.safetensors",
|
| 98 |
+
"model.layers.16.mlp.up_proj.weight": "model-00002-of-00003.safetensors",
|
| 99 |
+
"model.layers.16.post_attention_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 100 |
+
"model.layers.16.self_attn.k_norm.weight": "model-00002-of-00003.safetensors",
|
| 101 |
+
"model.layers.16.self_attn.k_proj.weight": "model-00002-of-00003.safetensors",
|
| 102 |
+
"model.layers.16.self_attn.o_proj.weight": "model-00002-of-00003.safetensors",
|
| 103 |
+
"model.layers.16.self_attn.q_norm.weight": "model-00002-of-00003.safetensors",
|
| 104 |
+
"model.layers.16.self_attn.q_proj.weight": "model-00002-of-00003.safetensors",
|
| 105 |
+
"model.layers.16.self_attn.v_proj.weight": "model-00002-of-00003.safetensors",
|
| 106 |
+
"model.layers.17.input_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 107 |
+
"model.layers.17.mlp.down_proj.weight": "model-00002-of-00003.safetensors",
|
| 108 |
+
"model.layers.17.mlp.gate_proj.weight": "model-00002-of-00003.safetensors",
|
| 109 |
+
"model.layers.17.mlp.up_proj.weight": "model-00002-of-00003.safetensors",
|
| 110 |
+
"model.layers.17.post_attention_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 111 |
+
"model.layers.17.self_attn.k_norm.weight": "model-00002-of-00003.safetensors",
|
| 112 |
+
"model.layers.17.self_attn.k_proj.weight": "model-00002-of-00003.safetensors",
|
| 113 |
+
"model.layers.17.self_attn.o_proj.weight": "model-00002-of-00003.safetensors",
|
| 114 |
+
"model.layers.17.self_attn.q_norm.weight": "model-00002-of-00003.safetensors",
|
| 115 |
+
"model.layers.17.self_attn.q_proj.weight": "model-00002-of-00003.safetensors",
|
| 116 |
+
"model.layers.17.self_attn.v_proj.weight": "model-00002-of-00003.safetensors",
|
| 117 |
+
"model.layers.18.input_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 118 |
+
"model.layers.18.mlp.down_proj.weight": "model-00002-of-00003.safetensors",
|
| 119 |
+
"model.layers.18.mlp.gate_proj.weight": "model-00002-of-00003.safetensors",
|
| 120 |
+
"model.layers.18.mlp.up_proj.weight": "model-00002-of-00003.safetensors",
|
| 121 |
+
"model.layers.18.post_attention_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 122 |
+
"model.layers.18.self_attn.k_norm.weight": "model-00002-of-00003.safetensors",
|
| 123 |
+
"model.layers.18.self_attn.k_proj.weight": "model-00002-of-00003.safetensors",
|
| 124 |
+
"model.layers.18.self_attn.o_proj.weight": "model-00002-of-00003.safetensors",
|
| 125 |
+
"model.layers.18.self_attn.q_norm.weight": "model-00002-of-00003.safetensors",
|
| 126 |
+
"model.layers.18.self_attn.q_proj.weight": "model-00002-of-00003.safetensors",
|
| 127 |
+
"model.layers.18.self_attn.v_proj.weight": "model-00002-of-00003.safetensors",
|
| 128 |
+
"model.layers.19.input_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 129 |
+
"model.layers.19.mlp.down_proj.weight": "model-00002-of-00003.safetensors",
|
| 130 |
+
"model.layers.19.mlp.gate_proj.weight": "model-00002-of-00003.safetensors",
|
| 131 |
+
"model.layers.19.mlp.up_proj.weight": "model-00002-of-00003.safetensors",
|
| 132 |
+
"model.layers.19.post_attention_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 133 |
+
"model.layers.19.self_attn.k_norm.weight": "model-00002-of-00003.safetensors",
|
| 134 |
+
"model.layers.19.self_attn.k_proj.weight": "model-00002-of-00003.safetensors",
|
| 135 |
+
"model.layers.19.self_attn.o_proj.weight": "model-00002-of-00003.safetensors",
|
| 136 |
+
"model.layers.19.self_attn.q_norm.weight": "model-00002-of-00003.safetensors",
|
| 137 |
+
"model.layers.19.self_attn.q_proj.weight": "model-00002-of-00003.safetensors",
|
| 138 |
+
"model.layers.19.self_attn.v_proj.weight": "model-00002-of-00003.safetensors",
|
| 139 |
+
"model.layers.2.input_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 140 |
+
"model.layers.2.mlp.down_proj.weight": "model-00001-of-00003.safetensors",
|
| 141 |
+
"model.layers.2.mlp.gate_proj.weight": "model-00001-of-00003.safetensors",
|
| 142 |
+
"model.layers.2.mlp.up_proj.weight": "model-00001-of-00003.safetensors",
|
| 143 |
+
"model.layers.2.post_attention_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 144 |
+
"model.layers.2.self_attn.k_norm.weight": "model-00001-of-00003.safetensors",
|
| 145 |
+
"model.layers.2.self_attn.k_proj.weight": "model-00001-of-00003.safetensors",
|
| 146 |
+
"model.layers.2.self_attn.o_proj.weight": "model-00001-of-00003.safetensors",
|
| 147 |
+
"model.layers.2.self_attn.q_norm.weight": "model-00001-of-00003.safetensors",
|
| 148 |
+
"model.layers.2.self_attn.q_proj.weight": "model-00001-of-00003.safetensors",
|
| 149 |
+
"model.layers.2.self_attn.v_proj.weight": "model-00001-of-00003.safetensors",
|
| 150 |
+
"model.layers.20.input_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 151 |
+
"model.layers.20.mlp.down_proj.weight": "model-00002-of-00003.safetensors",
|
| 152 |
+
"model.layers.20.mlp.gate_proj.weight": "model-00002-of-00003.safetensors",
|
| 153 |
+
"model.layers.20.mlp.up_proj.weight": "model-00002-of-00003.safetensors",
|
| 154 |
+
"model.layers.20.post_attention_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 155 |
+
"model.layers.20.self_attn.k_norm.weight": "model-00002-of-00003.safetensors",
|
| 156 |
+
"model.layers.20.self_attn.k_proj.weight": "model-00002-of-00003.safetensors",
|
| 157 |
+
"model.layers.20.self_attn.o_proj.weight": "model-00002-of-00003.safetensors",
|
| 158 |
+
"model.layers.20.self_attn.q_norm.weight": "model-00002-of-00003.safetensors",
|
| 159 |
+
"model.layers.20.self_attn.q_proj.weight": "model-00002-of-00003.safetensors",
|
| 160 |
+
"model.layers.20.self_attn.v_proj.weight": "model-00002-of-00003.safetensors",
|
| 161 |
+
"model.layers.21.input_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 162 |
+
"model.layers.21.mlp.down_proj.weight": "model-00002-of-00003.safetensors",
|
| 163 |
+
"model.layers.21.mlp.gate_proj.weight": "model-00002-of-00003.safetensors",
|
| 164 |
+
"model.layers.21.mlp.up_proj.weight": "model-00002-of-00003.safetensors",
|
| 165 |
+
"model.layers.21.post_attention_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 166 |
+
"model.layers.21.self_attn.k_norm.weight": "model-00002-of-00003.safetensors",
|
| 167 |
+
"model.layers.21.self_attn.k_proj.weight": "model-00002-of-00003.safetensors",
|
| 168 |
+
"model.layers.21.self_attn.o_proj.weight": "model-00002-of-00003.safetensors",
|
| 169 |
+
"model.layers.21.self_attn.q_norm.weight": "model-00002-of-00003.safetensors",
|
| 170 |
+
"model.layers.21.self_attn.q_proj.weight": "model-00002-of-00003.safetensors",
|
| 171 |
+
"model.layers.21.self_attn.v_proj.weight": "model-00002-of-00003.safetensors",
|
| 172 |
+
"model.layers.22.input_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 173 |
+
"model.layers.22.mlp.down_proj.weight": "model-00002-of-00003.safetensors",
|
| 174 |
+
"model.layers.22.mlp.gate_proj.weight": "model-00002-of-00003.safetensors",
|
| 175 |
+
"model.layers.22.mlp.up_proj.weight": "model-00002-of-00003.safetensors",
|
| 176 |
+
"model.layers.22.post_attention_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 177 |
+
"model.layers.22.self_attn.k_norm.weight": "model-00002-of-00003.safetensors",
|
| 178 |
+
"model.layers.22.self_attn.k_proj.weight": "model-00002-of-00003.safetensors",
|
| 179 |
+
"model.layers.22.self_attn.o_proj.weight": "model-00002-of-00003.safetensors",
|
| 180 |
+
"model.layers.22.self_attn.q_norm.weight": "model-00002-of-00003.safetensors",
|
| 181 |
+
"model.layers.22.self_attn.q_proj.weight": "model-00002-of-00003.safetensors",
|
| 182 |
+
"model.layers.22.self_attn.v_proj.weight": "model-00002-of-00003.safetensors",
|
| 183 |
+
"model.layers.23.input_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 184 |
+
"model.layers.23.mlp.down_proj.weight": "model-00002-of-00003.safetensors",
|
| 185 |
+
"model.layers.23.mlp.gate_proj.weight": "model-00002-of-00003.safetensors",
|
| 186 |
+
"model.layers.23.mlp.up_proj.weight": "model-00002-of-00003.safetensors",
|
| 187 |
+
"model.layers.23.post_attention_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 188 |
+
"model.layers.23.self_attn.k_norm.weight": "model-00002-of-00003.safetensors",
|
| 189 |
+
"model.layers.23.self_attn.k_proj.weight": "model-00002-of-00003.safetensors",
|
| 190 |
+
"model.layers.23.self_attn.o_proj.weight": "model-00002-of-00003.safetensors",
|
| 191 |
+
"model.layers.23.self_attn.q_norm.weight": "model-00002-of-00003.safetensors",
|
| 192 |
+
"model.layers.23.self_attn.q_proj.weight": "model-00002-of-00003.safetensors",
|
| 193 |
+
"model.layers.23.self_attn.v_proj.weight": "model-00002-of-00003.safetensors",
|
| 194 |
+
"model.layers.24.input_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 195 |
+
"model.layers.24.mlp.down_proj.weight": "model-00002-of-00003.safetensors",
|
| 196 |
+
"model.layers.24.mlp.gate_proj.weight": "model-00002-of-00003.safetensors",
|
| 197 |
+
"model.layers.24.mlp.up_proj.weight": "model-00002-of-00003.safetensors",
|
| 198 |
+
"model.layers.24.post_attention_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 199 |
+
"model.layers.24.self_attn.k_norm.weight": "model-00002-of-00003.safetensors",
|
| 200 |
+
"model.layers.24.self_attn.k_proj.weight": "model-00002-of-00003.safetensors",
|
| 201 |
+
"model.layers.24.self_attn.o_proj.weight": "model-00002-of-00003.safetensors",
|
| 202 |
+
"model.layers.24.self_attn.q_norm.weight": "model-00002-of-00003.safetensors",
|
| 203 |
+
"model.layers.24.self_attn.q_proj.weight": "model-00002-of-00003.safetensors",
|
| 204 |
+
"model.layers.24.self_attn.v_proj.weight": "model-00002-of-00003.safetensors",
|
| 205 |
+
"model.layers.25.input_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 206 |
+
"model.layers.25.mlp.down_proj.weight": "model-00002-of-00003.safetensors",
|
| 207 |
+
"model.layers.25.mlp.gate_proj.weight": "model-00002-of-00003.safetensors",
|
| 208 |
+
"model.layers.25.mlp.up_proj.weight": "model-00002-of-00003.safetensors",
|
| 209 |
+
"model.layers.25.post_attention_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 210 |
+
"model.layers.25.self_attn.k_norm.weight": "model-00002-of-00003.safetensors",
|
| 211 |
+
"model.layers.25.self_attn.k_proj.weight": "model-00002-of-00003.safetensors",
|
| 212 |
+
"model.layers.25.self_attn.o_proj.weight": "model-00002-of-00003.safetensors",
|
| 213 |
+
"model.layers.25.self_attn.q_norm.weight": "model-00002-of-00003.safetensors",
|
| 214 |
+
"model.layers.25.self_attn.q_proj.weight": "model-00002-of-00003.safetensors",
|
| 215 |
+
"model.layers.25.self_attn.v_proj.weight": "model-00002-of-00003.safetensors",
|
| 216 |
+
"model.layers.26.input_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 217 |
+
"model.layers.26.mlp.down_proj.weight": "model-00002-of-00003.safetensors",
|
| 218 |
+
"model.layers.26.mlp.gate_proj.weight": "model-00002-of-00003.safetensors",
|
| 219 |
+
"model.layers.26.mlp.up_proj.weight": "model-00002-of-00003.safetensors",
|
| 220 |
+
"model.layers.26.post_attention_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 221 |
+
"model.layers.26.self_attn.k_norm.weight": "model-00002-of-00003.safetensors",
|
| 222 |
+
"model.layers.26.self_attn.k_proj.weight": "model-00002-of-00003.safetensors",
|
| 223 |
+
"model.layers.26.self_attn.o_proj.weight": "model-00002-of-00003.safetensors",
|
| 224 |
+
"model.layers.26.self_attn.q_norm.weight": "model-00002-of-00003.safetensors",
|
| 225 |
+
"model.layers.26.self_attn.q_proj.weight": "model-00002-of-00003.safetensors",
|
| 226 |
+
"model.layers.26.self_attn.v_proj.weight": "model-00002-of-00003.safetensors",
|
| 227 |
+
"model.layers.27.input_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 228 |
+
"model.layers.27.mlp.down_proj.weight": "model-00002-of-00003.safetensors",
|
| 229 |
+
"model.layers.27.mlp.gate_proj.weight": "model-00002-of-00003.safetensors",
|
| 230 |
+
"model.layers.27.mlp.up_proj.weight": "model-00002-of-00003.safetensors",
|
| 231 |
+
"model.layers.27.post_attention_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 232 |
+
"model.layers.27.self_attn.k_norm.weight": "model-00002-of-00003.safetensors",
|
| 233 |
+
"model.layers.27.self_attn.k_proj.weight": "model-00002-of-00003.safetensors",
|
| 234 |
+
"model.layers.27.self_attn.o_proj.weight": "model-00002-of-00003.safetensors",
|
| 235 |
+
"model.layers.27.self_attn.q_norm.weight": "model-00002-of-00003.safetensors",
|
| 236 |
+
"model.layers.27.self_attn.q_proj.weight": "model-00002-of-00003.safetensors",
|
| 237 |
+
"model.layers.27.self_attn.v_proj.weight": "model-00002-of-00003.safetensors",
|
| 238 |
+
"model.layers.28.input_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 239 |
+
"model.layers.28.mlp.down_proj.weight": "model-00002-of-00003.safetensors",
|
| 240 |
+
"model.layers.28.mlp.gate_proj.weight": "model-00002-of-00003.safetensors",
|
| 241 |
+
"model.layers.28.mlp.up_proj.weight": "model-00002-of-00003.safetensors",
|
| 242 |
+
"model.layers.28.post_attention_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 243 |
+
"model.layers.28.self_attn.k_norm.weight": "model-00002-of-00003.safetensors",
|
| 244 |
+
"model.layers.28.self_attn.k_proj.weight": "model-00002-of-00003.safetensors",
|
| 245 |
+
"model.layers.28.self_attn.o_proj.weight": "model-00002-of-00003.safetensors",
|
| 246 |
+
"model.layers.28.self_attn.q_norm.weight": "model-00002-of-00003.safetensors",
|
| 247 |
+
"model.layers.28.self_attn.q_proj.weight": "model-00002-of-00003.safetensors",
|
| 248 |
+
"model.layers.28.self_attn.v_proj.weight": "model-00002-of-00003.safetensors",
|
| 249 |
+
"model.layers.29.input_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 250 |
+
"model.layers.29.mlp.down_proj.weight": "model-00002-of-00003.safetensors",
|
| 251 |
+
"model.layers.29.mlp.gate_proj.weight": "model-00002-of-00003.safetensors",
|
| 252 |
+
"model.layers.29.mlp.up_proj.weight": "model-00002-of-00003.safetensors",
|
| 253 |
+
"model.layers.29.post_attention_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 254 |
+
"model.layers.29.self_attn.k_norm.weight": "model-00002-of-00003.safetensors",
|
| 255 |
+
"model.layers.29.self_attn.k_proj.weight": "model-00002-of-00003.safetensors",
|
| 256 |
+
"model.layers.29.self_attn.o_proj.weight": "model-00002-of-00003.safetensors",
|
| 257 |
+
"model.layers.29.self_attn.q_norm.weight": "model-00002-of-00003.safetensors",
|
| 258 |
+
"model.layers.29.self_attn.q_proj.weight": "model-00002-of-00003.safetensors",
|
| 259 |
+
"model.layers.29.self_attn.v_proj.weight": "model-00002-of-00003.safetensors",
|
| 260 |
+
"model.layers.3.input_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 261 |
+
"model.layers.3.mlp.down_proj.weight": "model-00001-of-00003.safetensors",
|
| 262 |
+
"model.layers.3.mlp.gate_proj.weight": "model-00001-of-00003.safetensors",
|
| 263 |
+
"model.layers.3.mlp.up_proj.weight": "model-00001-of-00003.safetensors",
|
| 264 |
+
"model.layers.3.post_attention_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 265 |
+
"model.layers.3.self_attn.k_norm.weight": "model-00001-of-00003.safetensors",
|
| 266 |
+
"model.layers.3.self_attn.k_proj.weight": "model-00001-of-00003.safetensors",
|
| 267 |
+
"model.layers.3.self_attn.o_proj.weight": "model-00001-of-00003.safetensors",
|
| 268 |
+
"model.layers.3.self_attn.q_norm.weight": "model-00001-of-00003.safetensors",
|
| 269 |
+
"model.layers.3.self_attn.q_proj.weight": "model-00001-of-00003.safetensors",
|
| 270 |
+
"model.layers.3.self_attn.v_proj.weight": "model-00001-of-00003.safetensors",
|
| 271 |
+
"model.layers.30.input_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 272 |
+
"model.layers.30.mlp.down_proj.weight": "model-00002-of-00003.safetensors",
|
| 273 |
+
"model.layers.30.mlp.gate_proj.weight": "model-00002-of-00003.safetensors",
|
| 274 |
+
"model.layers.30.mlp.up_proj.weight": "model-00002-of-00003.safetensors",
|
| 275 |
+
"model.layers.30.post_attention_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 276 |
+
"model.layers.30.self_attn.k_norm.weight": "model-00002-of-00003.safetensors",
|
| 277 |
+
"model.layers.30.self_attn.k_proj.weight": "model-00002-of-00003.safetensors",
|
| 278 |
+
"model.layers.30.self_attn.o_proj.weight": "model-00002-of-00003.safetensors",
|
| 279 |
+
"model.layers.30.self_attn.q_norm.weight": "model-00002-of-00003.safetensors",
|
| 280 |
+
"model.layers.30.self_attn.q_proj.weight": "model-00002-of-00003.safetensors",
|
| 281 |
+
"model.layers.30.self_attn.v_proj.weight": "model-00002-of-00003.safetensors",
|
| 282 |
+
"model.layers.31.input_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 283 |
+
"model.layers.31.mlp.down_proj.weight": "model-00002-of-00003.safetensors",
|
| 284 |
+
"model.layers.31.mlp.gate_proj.weight": "model-00002-of-00003.safetensors",
|
| 285 |
+
"model.layers.31.mlp.up_proj.weight": "model-00002-of-00003.safetensors",
|
| 286 |
+
"model.layers.31.post_attention_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 287 |
+
"model.layers.31.self_attn.k_norm.weight": "model-00002-of-00003.safetensors",
|
| 288 |
+
"model.layers.31.self_attn.k_proj.weight": "model-00002-of-00003.safetensors",
|
| 289 |
+
"model.layers.31.self_attn.o_proj.weight": "model-00002-of-00003.safetensors",
|
| 290 |
+
"model.layers.31.self_attn.q_norm.weight": "model-00002-of-00003.safetensors",
|
| 291 |
+
"model.layers.31.self_attn.q_proj.weight": "model-00002-of-00003.safetensors",
|
| 292 |
+
"model.layers.31.self_attn.v_proj.weight": "model-00002-of-00003.safetensors",
|
| 293 |
+
"model.layers.32.input_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 294 |
+
"model.layers.32.mlp.down_proj.weight": "model-00002-of-00003.safetensors",
|
| 295 |
+
"model.layers.32.mlp.gate_proj.weight": "model-00002-of-00003.safetensors",
|
| 296 |
+
"model.layers.32.mlp.up_proj.weight": "model-00002-of-00003.safetensors",
|
| 297 |
+
"model.layers.32.post_attention_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 298 |
+
"model.layers.32.self_attn.k_norm.weight": "model-00002-of-00003.safetensors",
|
| 299 |
+
"model.layers.32.self_attn.k_proj.weight": "model-00002-of-00003.safetensors",
|
| 300 |
+
"model.layers.32.self_attn.o_proj.weight": "model-00002-of-00003.safetensors",
|
| 301 |
+
"model.layers.32.self_attn.q_norm.weight": "model-00002-of-00003.safetensors",
|
| 302 |
+
"model.layers.32.self_attn.q_proj.weight": "model-00002-of-00003.safetensors",
|
| 303 |
+
"model.layers.32.self_attn.v_proj.weight": "model-00002-of-00003.safetensors",
|
| 304 |
+
"model.layers.33.input_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 305 |
+
"model.layers.33.mlp.down_proj.weight": "model-00002-of-00003.safetensors",
|
| 306 |
+
"model.layers.33.mlp.gate_proj.weight": "model-00002-of-00003.safetensors",
|
| 307 |
+
"model.layers.33.mlp.up_proj.weight": "model-00002-of-00003.safetensors",
|
| 308 |
+
"model.layers.33.post_attention_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 309 |
+
"model.layers.33.self_attn.k_norm.weight": "model-00002-of-00003.safetensors",
|
| 310 |
+
"model.layers.33.self_attn.k_proj.weight": "model-00002-of-00003.safetensors",
|
| 311 |
+
"model.layers.33.self_attn.o_proj.weight": "model-00002-of-00003.safetensors",
|
| 312 |
+
"model.layers.33.self_attn.q_norm.weight": "model-00002-of-00003.safetensors",
|
| 313 |
+
"model.layers.33.self_attn.q_proj.weight": "model-00002-of-00003.safetensors",
|
| 314 |
+
"model.layers.33.self_attn.v_proj.weight": "model-00002-of-00003.safetensors",
|
| 315 |
+
"model.layers.34.input_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 316 |
+
"model.layers.34.mlp.down_proj.weight": "model-00002-of-00003.safetensors",
|
| 317 |
+
"model.layers.34.mlp.gate_proj.weight": "model-00002-of-00003.safetensors",
|
| 318 |
+
"model.layers.34.mlp.up_proj.weight": "model-00002-of-00003.safetensors",
|
| 319 |
+
"model.layers.34.post_attention_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 320 |
+
"model.layers.34.self_attn.k_norm.weight": "model-00002-of-00003.safetensors",
|
| 321 |
+
"model.layers.34.self_attn.k_proj.weight": "model-00002-of-00003.safetensors",
|
| 322 |
+
"model.layers.34.self_attn.o_proj.weight": "model-00002-of-00003.safetensors",
|
| 323 |
+
"model.layers.34.self_attn.q_norm.weight": "model-00002-of-00003.safetensors",
|
| 324 |
+
"model.layers.34.self_attn.q_proj.weight": "model-00002-of-00003.safetensors",
|
| 325 |
+
"model.layers.34.self_attn.v_proj.weight": "model-00002-of-00003.safetensors",
|
| 326 |
+
"model.layers.35.input_layernorm.weight": "model-00003-of-00003.safetensors",
|
| 327 |
+
"model.layers.35.mlp.down_proj.weight": "model-00003-of-00003.safetensors",
|
| 328 |
+
"model.layers.35.mlp.gate_proj.weight": "model-00002-of-00003.safetensors",
|
| 329 |
+
"model.layers.35.mlp.up_proj.weight": "model-00003-of-00003.safetensors",
|
| 330 |
+
"model.layers.35.post_attention_layernorm.weight": "model-00003-of-00003.safetensors",
|
| 331 |
+
"model.layers.35.self_attn.k_norm.weight": "model-00002-of-00003.safetensors",
|
| 332 |
+
"model.layers.35.self_attn.k_proj.weight": "model-00002-of-00003.safetensors",
|
| 333 |
+
"model.layers.35.self_attn.o_proj.weight": "model-00002-of-00003.safetensors",
|
| 334 |
+
"model.layers.35.self_attn.q_norm.weight": "model-00002-of-00003.safetensors",
|
| 335 |
+
"model.layers.35.self_attn.q_proj.weight": "model-00002-of-00003.safetensors",
|
| 336 |
+
"model.layers.35.self_attn.v_proj.weight": "model-00002-of-00003.safetensors",
|
| 337 |
+
"model.layers.4.input_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 338 |
+
"model.layers.4.mlp.down_proj.weight": "model-00001-of-00003.safetensors",
|
| 339 |
+
"model.layers.4.mlp.gate_proj.weight": "model-00001-of-00003.safetensors",
|
| 340 |
+
"model.layers.4.mlp.up_proj.weight": "model-00001-of-00003.safetensors",
|
| 341 |
+
"model.layers.4.post_attention_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 342 |
+
"model.layers.4.self_attn.k_norm.weight": "model-00001-of-00003.safetensors",
|
| 343 |
+
"model.layers.4.self_attn.k_proj.weight": "model-00001-of-00003.safetensors",
|
| 344 |
+
"model.layers.4.self_attn.o_proj.weight": "model-00001-of-00003.safetensors",
|
| 345 |
+
"model.layers.4.self_attn.q_norm.weight": "model-00001-of-00003.safetensors",
|
| 346 |
+
"model.layers.4.self_attn.q_proj.weight": "model-00001-of-00003.safetensors",
|
| 347 |
+
"model.layers.4.self_attn.v_proj.weight": "model-00001-of-00003.safetensors",
|
| 348 |
+
"model.layers.5.input_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 349 |
+
"model.layers.5.mlp.down_proj.weight": "model-00001-of-00003.safetensors",
|
| 350 |
+
"model.layers.5.mlp.gate_proj.weight": "model-00001-of-00003.safetensors",
|
| 351 |
+
"model.layers.5.mlp.up_proj.weight": "model-00001-of-00003.safetensors",
|
| 352 |
+
"model.layers.5.post_attention_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 353 |
+
"model.layers.5.self_attn.k_norm.weight": "model-00001-of-00003.safetensors",
|
| 354 |
+
"model.layers.5.self_attn.k_proj.weight": "model-00001-of-00003.safetensors",
|
| 355 |
+
"model.layers.5.self_attn.o_proj.weight": "model-00001-of-00003.safetensors",
|
| 356 |
+
"model.layers.5.self_attn.q_norm.weight": "model-00001-of-00003.safetensors",
|
| 357 |
+
"model.layers.5.self_attn.q_proj.weight": "model-00001-of-00003.safetensors",
|
| 358 |
+
"model.layers.5.self_attn.v_proj.weight": "model-00001-of-00003.safetensors",
|
| 359 |
+
"model.layers.6.input_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 360 |
+
"model.layers.6.mlp.down_proj.weight": "model-00001-of-00003.safetensors",
|
| 361 |
+
"model.layers.6.mlp.gate_proj.weight": "model-00001-of-00003.safetensors",
|
| 362 |
+
"model.layers.6.mlp.up_proj.weight": "model-00001-of-00003.safetensors",
|
| 363 |
+
"model.layers.6.post_attention_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 364 |
+
"model.layers.6.self_attn.k_norm.weight": "model-00001-of-00003.safetensors",
|
| 365 |
+
"model.layers.6.self_attn.k_proj.weight": "model-00001-of-00003.safetensors",
|
| 366 |
+
"model.layers.6.self_attn.o_proj.weight": "model-00001-of-00003.safetensors",
|
| 367 |
+
"model.layers.6.self_attn.q_norm.weight": "model-00001-of-00003.safetensors",
|
| 368 |
+
"model.layers.6.self_attn.q_proj.weight": "model-00001-of-00003.safetensors",
|
| 369 |
+
"model.layers.6.self_attn.v_proj.weight": "model-00001-of-00003.safetensors",
|
| 370 |
+
"model.layers.7.input_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 371 |
+
"model.layers.7.mlp.down_proj.weight": "model-00001-of-00003.safetensors",
|
| 372 |
+
"model.layers.7.mlp.gate_proj.weight": "model-00001-of-00003.safetensors",
|
| 373 |
+
"model.layers.7.mlp.up_proj.weight": "model-00001-of-00003.safetensors",
|
| 374 |
+
"model.layers.7.post_attention_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 375 |
+
"model.layers.7.self_attn.k_norm.weight": "model-00001-of-00003.safetensors",
|
| 376 |
+
"model.layers.7.self_attn.k_proj.weight": "model-00001-of-00003.safetensors",
|
| 377 |
+
"model.layers.7.self_attn.o_proj.weight": "model-00001-of-00003.safetensors",
|
| 378 |
+
"model.layers.7.self_attn.q_norm.weight": "model-00001-of-00003.safetensors",
|
| 379 |
+
"model.layers.7.self_attn.q_proj.weight": "model-00001-of-00003.safetensors",
|
| 380 |
+
"model.layers.7.self_attn.v_proj.weight": "model-00001-of-00003.safetensors",
|
| 381 |
+
"model.layers.8.input_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 382 |
+
"model.layers.8.mlp.down_proj.weight": "model-00001-of-00003.safetensors",
|
| 383 |
+
"model.layers.8.mlp.gate_proj.weight": "model-00001-of-00003.safetensors",
|
| 384 |
+
"model.layers.8.mlp.up_proj.weight": "model-00001-of-00003.safetensors",
|
| 385 |
+
"model.layers.8.post_attention_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 386 |
+
"model.layers.8.self_attn.k_norm.weight": "model-00001-of-00003.safetensors",
|
| 387 |
+
"model.layers.8.self_attn.k_proj.weight": "model-00001-of-00003.safetensors",
|
| 388 |
+
"model.layers.8.self_attn.o_proj.weight": "model-00001-of-00003.safetensors",
|
| 389 |
+
"model.layers.8.self_attn.q_norm.weight": "model-00001-of-00003.safetensors",
|
| 390 |
+
"model.layers.8.self_attn.q_proj.weight": "model-00001-of-00003.safetensors",
|
| 391 |
+
"model.layers.8.self_attn.v_proj.weight": "model-00001-of-00003.safetensors",
|
| 392 |
+
"model.layers.9.input_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 393 |
+
"model.layers.9.mlp.down_proj.weight": "model-00001-of-00003.safetensors",
|
| 394 |
+
"model.layers.9.mlp.gate_proj.weight": "model-00001-of-00003.safetensors",
|
| 395 |
+
"model.layers.9.mlp.up_proj.weight": "model-00001-of-00003.safetensors",
|
| 396 |
+
"model.layers.9.post_attention_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 397 |
+
"model.layers.9.self_attn.k_norm.weight": "model-00001-of-00003.safetensors",
|
| 398 |
+
"model.layers.9.self_attn.k_proj.weight": "model-00001-of-00003.safetensors",
|
| 399 |
+
"model.layers.9.self_attn.o_proj.weight": "model-00001-of-00003.safetensors",
|
| 400 |
+
"model.layers.9.self_attn.q_norm.weight": "model-00001-of-00003.safetensors",
|
| 401 |
+
"model.layers.9.self_attn.q_proj.weight": "model-00001-of-00003.safetensors",
|
| 402 |
+
"model.layers.9.self_attn.v_proj.weight": "model-00001-of-00003.safetensors",
|
| 403 |
+
"model.norm.weight": "model-00003-of-00003.safetensors"
|
| 404 |
+
}
|
| 405 |
+
}
|
models/Qwen3-4B-Instruct-2507/tokenizer.json
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:aeb13307a71acd8fe81861d94ad54ab689df773318809eed3cbe794b4492dae4
|
| 3 |
+
size 11422654
|
models/Qwen3-4B-Instruct-2507/tokenizer_config.json
ADDED
|
@@ -0,0 +1,239 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"add_prefix_space": false,
|
| 3 |
+
"added_tokens_decoder": {
|
| 4 |
+
"151643": {
|
| 5 |
+
"content": "<|endoftext|>",
|
| 6 |
+
"lstrip": false,
|
| 7 |
+
"normalized": false,
|
| 8 |
+
"rstrip": false,
|
| 9 |
+
"single_word": false,
|
| 10 |
+
"special": true
|
| 11 |
+
},
|
| 12 |
+
"151644": {
|
| 13 |
+
"content": "<|im_start|>",
|
| 14 |
+
"lstrip": false,
|
| 15 |
+
"normalized": false,
|
| 16 |
+
"rstrip": false,
|
| 17 |
+
"single_word": false,
|
| 18 |
+
"special": true
|
| 19 |
+
},
|
| 20 |
+
"151645": {
|
| 21 |
+
"content": "<|im_end|>",
|
| 22 |
+
"lstrip": false,
|
| 23 |
+
"normalized": false,
|
| 24 |
+
"rstrip": false,
|
| 25 |
+
"single_word": false,
|
| 26 |
+
"special": true
|
| 27 |
+
},
|
| 28 |
+
"151646": {
|
| 29 |
+
"content": "<|object_ref_start|>",
|
| 30 |
+
"lstrip": false,
|
| 31 |
+
"normalized": false,
|
| 32 |
+
"rstrip": false,
|
| 33 |
+
"single_word": false,
|
| 34 |
+
"special": true
|
| 35 |
+
},
|
| 36 |
+
"151647": {
|
| 37 |
+
"content": "<|object_ref_end|>",
|
| 38 |
+
"lstrip": false,
|
| 39 |
+
"normalized": false,
|
| 40 |
+
"rstrip": false,
|
| 41 |
+
"single_word": false,
|
| 42 |
+
"special": true
|
| 43 |
+
},
|
| 44 |
+
"151648": {
|
| 45 |
+
"content": "<|box_start|>",
|
| 46 |
+
"lstrip": false,
|
| 47 |
+
"normalized": false,
|
| 48 |
+
"rstrip": false,
|
| 49 |
+
"single_word": false,
|
| 50 |
+
"special": true
|
| 51 |
+
},
|
| 52 |
+
"151649": {
|
| 53 |
+
"content": "<|box_end|>",
|
| 54 |
+
"lstrip": false,
|
| 55 |
+
"normalized": false,
|
| 56 |
+
"rstrip": false,
|
| 57 |
+
"single_word": false,
|
| 58 |
+
"special": true
|
| 59 |
+
},
|
| 60 |
+
"151650": {
|
| 61 |
+
"content": "<|quad_start|>",
|
| 62 |
+
"lstrip": false,
|
| 63 |
+
"normalized": false,
|
| 64 |
+
"rstrip": false,
|
| 65 |
+
"single_word": false,
|
| 66 |
+
"special": true
|
| 67 |
+
},
|
| 68 |
+
"151651": {
|
| 69 |
+
"content": "<|quad_end|>",
|
| 70 |
+
"lstrip": false,
|
| 71 |
+
"normalized": false,
|
| 72 |
+
"rstrip": false,
|
| 73 |
+
"single_word": false,
|
| 74 |
+
"special": true
|
| 75 |
+
},
|
| 76 |
+
"151652": {
|
| 77 |
+
"content": "<|vision_start|>",
|
| 78 |
+
"lstrip": false,
|
| 79 |
+
"normalized": false,
|
| 80 |
+
"rstrip": false,
|
| 81 |
+
"single_word": false,
|
| 82 |
+
"special": true
|
| 83 |
+
},
|
| 84 |
+
"151653": {
|
| 85 |
+
"content": "<|vision_end|>",
|
| 86 |
+
"lstrip": false,
|
| 87 |
+
"normalized": false,
|
| 88 |
+
"rstrip": false,
|
| 89 |
+
"single_word": false,
|
| 90 |
+
"special": true
|
| 91 |
+
},
|
| 92 |
+
"151654": {
|
| 93 |
+
"content": "<|vision_pad|>",
|
| 94 |
+
"lstrip": false,
|
| 95 |
+
"normalized": false,
|
| 96 |
+
"rstrip": false,
|
| 97 |
+
"single_word": false,
|
| 98 |
+
"special": true
|
| 99 |
+
},
|
| 100 |
+
"151655": {
|
| 101 |
+
"content": "<|image_pad|>",
|
| 102 |
+
"lstrip": false,
|
| 103 |
+
"normalized": false,
|
| 104 |
+
"rstrip": false,
|
| 105 |
+
"single_word": false,
|
| 106 |
+
"special": true
|
| 107 |
+
},
|
| 108 |
+
"151656": {
|
| 109 |
+
"content": "<|video_pad|>",
|
| 110 |
+
"lstrip": false,
|
| 111 |
+
"normalized": false,
|
| 112 |
+
"rstrip": false,
|
| 113 |
+
"single_word": false,
|
| 114 |
+
"special": true
|
| 115 |
+
},
|
| 116 |
+
"151657": {
|
| 117 |
+
"content": "<tool_call>",
|
| 118 |
+
"lstrip": false,
|
| 119 |
+
"normalized": false,
|
| 120 |
+
"rstrip": false,
|
| 121 |
+
"single_word": false,
|
| 122 |
+
"special": false
|
| 123 |
+
},
|
| 124 |
+
"151658": {
|
| 125 |
+
"content": "</tool_call>",
|
| 126 |
+
"lstrip": false,
|
| 127 |
+
"normalized": false,
|
| 128 |
+
"rstrip": false,
|
| 129 |
+
"single_word": false,
|
| 130 |
+
"special": false
|
| 131 |
+
},
|
| 132 |
+
"151659": {
|
| 133 |
+
"content": "<|fim_prefix|>",
|
| 134 |
+
"lstrip": false,
|
| 135 |
+
"normalized": false,
|
| 136 |
+
"rstrip": false,
|
| 137 |
+
"single_word": false,
|
| 138 |
+
"special": false
|
| 139 |
+
},
|
| 140 |
+
"151660": {
|
| 141 |
+
"content": "<|fim_middle|>",
|
| 142 |
+
"lstrip": false,
|
| 143 |
+
"normalized": false,
|
| 144 |
+
"rstrip": false,
|
| 145 |
+
"single_word": false,
|
| 146 |
+
"special": false
|
| 147 |
+
},
|
| 148 |
+
"151661": {
|
| 149 |
+
"content": "<|fim_suffix|>",
|
| 150 |
+
"lstrip": false,
|
| 151 |
+
"normalized": false,
|
| 152 |
+
"rstrip": false,
|
| 153 |
+
"single_word": false,
|
| 154 |
+
"special": false
|
| 155 |
+
},
|
| 156 |
+
"151662": {
|
| 157 |
+
"content": "<|fim_pad|>",
|
| 158 |
+
"lstrip": false,
|
| 159 |
+
"normalized": false,
|
| 160 |
+
"rstrip": false,
|
| 161 |
+
"single_word": false,
|
| 162 |
+
"special": false
|
| 163 |
+
},
|
| 164 |
+
"151663": {
|
| 165 |
+
"content": "<|repo_name|>",
|
| 166 |
+
"lstrip": false,
|
| 167 |
+
"normalized": false,
|
| 168 |
+
"rstrip": false,
|
| 169 |
+
"single_word": false,
|
| 170 |
+
"special": false
|
| 171 |
+
},
|
| 172 |
+
"151664": {
|
| 173 |
+
"content": "<|file_sep|>",
|
| 174 |
+
"lstrip": false,
|
| 175 |
+
"normalized": false,
|
| 176 |
+
"rstrip": false,
|
| 177 |
+
"single_word": false,
|
| 178 |
+
"special": false
|
| 179 |
+
},
|
| 180 |
+
"151665": {
|
| 181 |
+
"content": "<tool_response>",
|
| 182 |
+
"lstrip": false,
|
| 183 |
+
"normalized": false,
|
| 184 |
+
"rstrip": false,
|
| 185 |
+
"single_word": false,
|
| 186 |
+
"special": false
|
| 187 |
+
},
|
| 188 |
+
"151666": {
|
| 189 |
+
"content": "</tool_response>",
|
| 190 |
+
"lstrip": false,
|
| 191 |
+
"normalized": false,
|
| 192 |
+
"rstrip": false,
|
| 193 |
+
"single_word": false,
|
| 194 |
+
"special": false
|
| 195 |
+
},
|
| 196 |
+
"151667": {
|
| 197 |
+
"content": "<think>",
|
| 198 |
+
"lstrip": false,
|
| 199 |
+
"normalized": false,
|
| 200 |
+
"rstrip": false,
|
| 201 |
+
"single_word": false,
|
| 202 |
+
"special": false
|
| 203 |
+
},
|
| 204 |
+
"151668": {
|
| 205 |
+
"content": "</think>",
|
| 206 |
+
"lstrip": false,
|
| 207 |
+
"normalized": false,
|
| 208 |
+
"rstrip": false,
|
| 209 |
+
"single_word": false,
|
| 210 |
+
"special": false
|
| 211 |
+
}
|
| 212 |
+
},
|
| 213 |
+
"additional_special_tokens": [
|
| 214 |
+
"<|im_start|>",
|
| 215 |
+
"<|im_end|>",
|
| 216 |
+
"<|object_ref_start|>",
|
| 217 |
+
"<|object_ref_end|>",
|
| 218 |
+
"<|box_start|>",
|
| 219 |
+
"<|box_end|>",
|
| 220 |
+
"<|quad_start|>",
|
| 221 |
+
"<|quad_end|>",
|
| 222 |
+
"<|vision_start|>",
|
| 223 |
+
"<|vision_end|>",
|
| 224 |
+
"<|vision_pad|>",
|
| 225 |
+
"<|image_pad|>",
|
| 226 |
+
"<|video_pad|>"
|
| 227 |
+
],
|
| 228 |
+
"bos_token": null,
|
| 229 |
+
"chat_template": "{%- if tools %}\n {{- '<|im_start|>system\\n' }}\n {%- if messages[0].role == 'system' %}\n {{- messages[0].content + '\\n\\n' }}\n {%- endif %}\n {{- \"# Tools\\n\\nYou may call one or more functions to assist with the user query.\\n\\nYou are provided with function signatures within <tools></tools> XML tags:\\n<tools>\" }}\n {%- for tool in tools %}\n {{- \"\\n\" }}\n {{- tool | tojson }}\n {%- endfor %}\n {{- \"\\n</tools>\\n\\nFor each function call, return a json object with function name and arguments within <tool_call></tool_call> XML tags:\\n<tool_call>\\n{\\\"name\\\": <function-name>, \\\"arguments\\\": <args-json-object>}\\n</tool_call><|im_end|>\\n\" }}\n{%- else %}\n {%- if messages[0].role == 'system' %}\n {{- '<|im_start|>system\\n' + messages[0].content + '<|im_end|>\\n' }}\n {%- endif %}\n{%- endif %}\n{%- for message in messages %}\n {%- if message.content is string %}\n {%- set content = message.content %}\n {%- else %}\n {%- set content = '' %}\n {%- endif %}\n {%- if (message.role == \"user\") or (message.role == \"system\" and not loop.first) %}\n {{- '<|im_start|>' + message.role + '\\n' + content + '<|im_end|>' + '\\n' }}\n {%- elif message.role == \"assistant\" %}\n {{- '<|im_start|>' + message.role + '\\n' + content }}\n {%- if message.tool_calls %}\n {%- for tool_call in message.tool_calls %}\n {%- if (loop.first and content) or (not loop.first) %}\n {{- '\\n' }}\n {%- endif %}\n {%- if tool_call.function %}\n {%- set tool_call = tool_call.function %}\n {%- endif %}\n {{- '<tool_call>\\n{\"name\": \"' }}\n {{- tool_call.name }}\n {{- '\", \"arguments\": ' }}\n {%- if tool_call.arguments is string %}\n {{- tool_call.arguments }}\n {%- else %}\n {{- tool_call.arguments | tojson }}\n {%- endif %}\n {{- '}\\n</tool_call>' }}\n {%- endfor %}\n {%- endif %}\n {{- '<|im_end|>\\n' }}\n {%- elif message.role == \"tool\" %}\n {%- if loop.first or (messages[loop.index0 - 1].role != \"tool\") %}\n {{- '<|im_start|>user' }}\n {%- endif %}\n {{- '\\n<tool_response>\\n' }}\n {{- content }}\n {{- '\\n</tool_response>' }}\n {%- if loop.last or (messages[loop.index0 + 1].role != \"tool\") %}\n {{- '<|im_end|>\\n' }}\n {%- endif %}\n {%- endif %}\n{%- endfor %}\n{%- if add_generation_prompt %}\n {{- '<|im_start|>assistant\\n' }}\n{%- endif %}",
|
| 230 |
+
"clean_up_tokenization_spaces": false,
|
| 231 |
+
"eos_token": "<|im_end|>",
|
| 232 |
+
"errors": "replace",
|
| 233 |
+
"model_max_length": 1010000,
|
| 234 |
+
"pad_token": "<|endoftext|>",
|
| 235 |
+
"split_special_tokens": false,
|
| 236 |
+
"tokenizer_class": "Qwen2Tokenizer",
|
| 237 |
+
"unk_token": null,
|
| 238 |
+
"add_bos_token": false
|
| 239 |
+
}
|
models/Qwen3-4B-Instruct-2507/vocab.json
ADDED
|
The diff for this file is too large to render.
See raw diff
|
|
|
models/Qwen3-Embedding-0.6B/.gitattributes
ADDED
|
@@ -0,0 +1,36 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
*.7z filter=lfs diff=lfs merge=lfs -text
|
| 2 |
+
*.arrow filter=lfs diff=lfs merge=lfs -text
|
| 3 |
+
*.bin filter=lfs diff=lfs merge=lfs -text
|
| 4 |
+
*.bz2 filter=lfs diff=lfs merge=lfs -text
|
| 5 |
+
*.ckpt filter=lfs diff=lfs merge=lfs -text
|
| 6 |
+
*.ftz filter=lfs diff=lfs merge=lfs -text
|
| 7 |
+
*.gz filter=lfs diff=lfs merge=lfs -text
|
| 8 |
+
*.h5 filter=lfs diff=lfs merge=lfs -text
|
| 9 |
+
*.joblib filter=lfs diff=lfs merge=lfs -text
|
| 10 |
+
*.lfs.* filter=lfs diff=lfs merge=lfs -text
|
| 11 |
+
*.mlmodel filter=lfs diff=lfs merge=lfs -text
|
| 12 |
+
*.model filter=lfs diff=lfs merge=lfs -text
|
| 13 |
+
*.msgpack filter=lfs diff=lfs merge=lfs -text
|
| 14 |
+
*.npy filter=lfs diff=lfs merge=lfs -text
|
| 15 |
+
*.npz filter=lfs diff=lfs merge=lfs -text
|
| 16 |
+
*.onnx filter=lfs diff=lfs merge=lfs -text
|
| 17 |
+
*.ot filter=lfs diff=lfs merge=lfs -text
|
| 18 |
+
*.parquet filter=lfs diff=lfs merge=lfs -text
|
| 19 |
+
*.pb filter=lfs diff=lfs merge=lfs -text
|
| 20 |
+
*.pickle filter=lfs diff=lfs merge=lfs -text
|
| 21 |
+
*.pkl filter=lfs diff=lfs merge=lfs -text
|
| 22 |
+
*.pt filter=lfs diff=lfs merge=lfs -text
|
| 23 |
+
*.pth filter=lfs diff=lfs merge=lfs -text
|
| 24 |
+
*.rar filter=lfs diff=lfs merge=lfs -text
|
| 25 |
+
*.safetensors filter=lfs diff=lfs merge=lfs -text
|
| 26 |
+
saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
| 27 |
+
*.tar.* filter=lfs diff=lfs merge=lfs -text
|
| 28 |
+
*.tar filter=lfs diff=lfs merge=lfs -text
|
| 29 |
+
*.tflite filter=lfs diff=lfs merge=lfs -text
|
| 30 |
+
*.tgz filter=lfs diff=lfs merge=lfs -text
|
| 31 |
+
*.wasm filter=lfs diff=lfs merge=lfs -text
|
| 32 |
+
*.xz filter=lfs diff=lfs merge=lfs -text
|
| 33 |
+
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 34 |
+
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
+
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
| 36 |
+
tokenizer.json filter=lfs diff=lfs merge=lfs -text
|
models/Qwen3-Embedding-0.6B/1_Pooling/config.json
ADDED
|
@@ -0,0 +1,10 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"word_embedding_dimension": 1024,
|
| 3 |
+
"pooling_mode_cls_token": false,
|
| 4 |
+
"pooling_mode_mean_tokens": false,
|
| 5 |
+
"pooling_mode_max_tokens": false,
|
| 6 |
+
"pooling_mode_mean_sqrt_len_tokens": false,
|
| 7 |
+
"pooling_mode_weightedmean_tokens": false,
|
| 8 |
+
"pooling_mode_lasttoken": true,
|
| 9 |
+
"include_prompt": true
|
| 10 |
+
}
|
models/Qwen3-Embedding-0.6B/README.md
ADDED
|
@@ -0,0 +1,292 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
---
|
| 2 |
+
license: apache-2.0
|
| 3 |
+
base_model:
|
| 4 |
+
- Qwen/Qwen3-0.6B-Base
|
| 5 |
+
tags:
|
| 6 |
+
- transformers
|
| 7 |
+
- sentence-transformers
|
| 8 |
+
- sentence-similarity
|
| 9 |
+
- feature-extraction
|
| 10 |
+
- text-embeddings-inference
|
| 11 |
+
---
|
| 12 |
+
# Qwen3-Embedding-0.6B
|
| 13 |
+
|
| 14 |
+
<p align="center">
|
| 15 |
+
<img src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/logo_qwen3.png" width="400"/>
|
| 16 |
+
<p>
|
| 17 |
+
|
| 18 |
+
## Highlights
|
| 19 |
+
|
| 20 |
+
The Qwen3 Embedding model series is the latest proprietary model of the Qwen family, specifically designed for text embedding and ranking tasks. Building upon the dense foundational models of the Qwen3 series, it provides a comprehensive range of text embeddings and reranking models in various sizes (0.6B, 4B, and 8B). This series inherits the exceptional multilingual capabilities, long-text understanding, and reasoning skills of its foundational model. The Qwen3 Embedding series represents significant advancements in multiple text embedding and ranking tasks, including text retrieval, code retrieval, text classification, text clustering, and bitext mining.
|
| 21 |
+
|
| 22 |
+
**Exceptional Versatility**: The embedding model has achieved state-of-the-art performance across a wide range of downstream application evaluations. The 8B size embedding model ranks **No.1** in the MTEB multilingual leaderboard (as of June 5, 2025, score **70.58**), while the reranking model excels in various text retrieval scenarios.
|
| 23 |
+
|
| 24 |
+
**Comprehensive Flexibility**: The Qwen3 Embedding series offers a full spectrum of sizes (from 0.6B to 8B) for both embedding and reranking models, catering to diverse use cases that prioritize efficiency and effectiveness. Developers can seamlessly combine these two modules. Additionally, the embedding model allows for flexible vector definitions across all dimensions, and both embedding and reranking models support user-defined instructions to enhance performance for specific tasks, languages, or scenarios.
|
| 25 |
+
|
| 26 |
+
**Multilingual Capability**: The Qwen3 Embedding series offer support for over 100 languages, thanks to the multilingual capabilites of Qwen3 models. This includes various programming languages, and provides robust multilingual, cross-lingual, and code retrieval capabilities.
|
| 27 |
+
|
| 28 |
+
## Model Overview
|
| 29 |
+
|
| 30 |
+
**Qwen3-Embedding-0.6B** has the following features:
|
| 31 |
+
|
| 32 |
+
- Model Type: Text Embedding
|
| 33 |
+
- Supported Languages: 100+ Languages
|
| 34 |
+
- Number of Parameters: 0.6B
|
| 35 |
+
- Context Length: 32k
|
| 36 |
+
- Embedding Dimension: Up to 1024, supports user-defined output dimensions ranging from 32 to 1024
|
| 37 |
+
|
| 38 |
+
For more details, including benchmark evaluation, hardware requirements, and inference performance, please refer to our [blog](https://qwenlm.github.io/blog/qwen3-embedding/), [GitHub](https://github.com/QwenLM/Qwen3-Embedding).
|
| 39 |
+
|
| 40 |
+
## Qwen3 Embedding Series Model list
|
| 41 |
+
|
| 42 |
+
| Model Type | Models | Size | Layers | Sequence Length | Embedding Dimension | MRL Support | Instruction Aware |
|
| 43 |
+
|------------------|----------------------|------|--------|-----------------|---------------------|-------------|----------------|
|
| 44 |
+
| Text Embedding | [Qwen3-Embedding-0.6B](https://huggingface.co/Qwen/Qwen3-Embedding-0.6B) | 0.6B | 28 | 32K | 1024 | Yes | Yes |
|
| 45 |
+
| Text Embedding | [Qwen3-Embedding-4B](https://huggingface.co/Qwen/Qwen3-Embedding-4B) | 4B | 36 | 32K | 2560 | Yes | Yes |
|
| 46 |
+
| Text Embedding | [Qwen3-Embedding-8B](https://huggingface.co/Qwen/Qwen3-Embedding-8B) | 8B | 36 | 32K | 4096 | Yes | Yes |
|
| 47 |
+
| Text Reranking | [Qwen3-Reranker-0.6B](https://huggingface.co/Qwen/Qwen3-Reranker-0.6B) | 0.6B | 28 | 32K | - | - | Yes |
|
| 48 |
+
| Text Reranking | [Qwen3-Reranker-4B](https://huggingface.co/Qwen/Qwen3-Reranker-4B) | 4B | 36 | 32K | - | - | Yes |
|
| 49 |
+
| Text Reranking | [Qwen3-Reranker-8B](https://huggingface.co/Qwen/Qwen3-Reranker-8B) | 8B | 36 | 32K | - | - | Yes |
|
| 50 |
+
|
| 51 |
+
> **Note**:
|
| 52 |
+
> - `MRL Support` indicates whether the embedding model supports custom dimensions for the final embedding.
|
| 53 |
+
> - `Instruction Aware` notes whether the embedding or reranking model supports customizing the input instruction according to different tasks.
|
| 54 |
+
> - Our evaluation indicates that, for most downstream tasks, using instructions (instruct) typically yields an improvement of 1% to 5% compared to not using them. Therefore, we recommend that developers create tailored instructions specific to their tasks and scenarios. In multilingual contexts, we also advise users to write their instructions in English, as most instructions utilized during the model training process were originally written in English.
|
| 55 |
+
|
| 56 |
+
## Usage
|
| 57 |
+
|
| 58 |
+
With Transformers versions earlier than 4.51.0, you may encounter the following error:
|
| 59 |
+
```
|
| 60 |
+
KeyError: 'qwen3'
|
| 61 |
+
```
|
| 62 |
+
|
| 63 |
+
### Sentence Transformers Usage
|
| 64 |
+
|
| 65 |
+
```python
|
| 66 |
+
# Requires transformers>=4.51.0
|
| 67 |
+
# Requires sentence-transformers>=2.7.0
|
| 68 |
+
|
| 69 |
+
from sentence_transformers import SentenceTransformer
|
| 70 |
+
|
| 71 |
+
# Load the model
|
| 72 |
+
model = SentenceTransformer("Qwen/Qwen3-Embedding-0.6B")
|
| 73 |
+
|
| 74 |
+
# We recommend enabling flash_attention_2 for better acceleration and memory saving,
|
| 75 |
+
# together with setting `padding_side` to "left":
|
| 76 |
+
# model = SentenceTransformer(
|
| 77 |
+
# "Qwen/Qwen3-Embedding-0.6B",
|
| 78 |
+
# model_kwargs={"attn_implementation": "flash_attention_2", "device_map": "auto"},
|
| 79 |
+
# tokenizer_kwargs={"padding_side": "left"},
|
| 80 |
+
# )
|
| 81 |
+
|
| 82 |
+
# The queries and documents to embed
|
| 83 |
+
queries = [
|
| 84 |
+
"What is the capital of China?",
|
| 85 |
+
"Explain gravity",
|
| 86 |
+
]
|
| 87 |
+
documents = [
|
| 88 |
+
"The capital of China is Beijing.",
|
| 89 |
+
"Gravity is a force that attracts two bodies towards each other. It gives weight to physical objects and is responsible for the movement of planets around the sun.",
|
| 90 |
+
]
|
| 91 |
+
|
| 92 |
+
# Encode the queries and documents. Note that queries benefit from using a prompt
|
| 93 |
+
# Here we use the prompt called "query" stored under `model.prompts`, but you can
|
| 94 |
+
# also pass your own prompt via the `prompt` argument
|
| 95 |
+
query_embeddings = model.encode(queries, prompt_name="query")
|
| 96 |
+
document_embeddings = model.encode(documents)
|
| 97 |
+
|
| 98 |
+
# Compute the (cosine) similarity between the query and document embeddings
|
| 99 |
+
similarity = model.similarity(query_embeddings, document_embeddings)
|
| 100 |
+
print(similarity)
|
| 101 |
+
# tensor([[0.7646, 0.1414],
|
| 102 |
+
# [0.1355, 0.6000]])
|
| 103 |
+
```
|
| 104 |
+
|
| 105 |
+
### Transformers Usage
|
| 106 |
+
|
| 107 |
+
```python
|
| 108 |
+
# Requires transformers>=4.51.0
|
| 109 |
+
|
| 110 |
+
import torch
|
| 111 |
+
import torch.nn.functional as F
|
| 112 |
+
|
| 113 |
+
from torch import Tensor
|
| 114 |
+
from transformers import AutoTokenizer, AutoModel
|
| 115 |
+
|
| 116 |
+
|
| 117 |
+
def last_token_pool(last_hidden_states: Tensor,
|
| 118 |
+
attention_mask: Tensor) -> Tensor:
|
| 119 |
+
left_padding = (attention_mask[:, -1].sum() == attention_mask.shape[0])
|
| 120 |
+
if left_padding:
|
| 121 |
+
return last_hidden_states[:, -1]
|
| 122 |
+
else:
|
| 123 |
+
sequence_lengths = attention_mask.sum(dim=1) - 1
|
| 124 |
+
batch_size = last_hidden_states.shape[0]
|
| 125 |
+
return last_hidden_states[torch.arange(batch_size, device=last_hidden_states.device), sequence_lengths]
|
| 126 |
+
|
| 127 |
+
|
| 128 |
+
def get_detailed_instruct(task_description: str, query: str) -> str:
|
| 129 |
+
return f'Instruct: {task_description}\nQuery:{query}'
|
| 130 |
+
|
| 131 |
+
# Each query must come with a one-sentence instruction that describes the task
|
| 132 |
+
task = 'Given a web search query, retrieve relevant passages that answer the query'
|
| 133 |
+
|
| 134 |
+
queries = [
|
| 135 |
+
get_detailed_instruct(task, 'What is the capital of China?'),
|
| 136 |
+
get_detailed_instruct(task, 'Explain gravity')
|
| 137 |
+
]
|
| 138 |
+
# No need to add instruction for retrieval documents
|
| 139 |
+
documents = [
|
| 140 |
+
"The capital of China is Beijing.",
|
| 141 |
+
"Gravity is a force that attracts two bodies towards each other. It gives weight to physical objects and is responsible for the movement of planets around the sun."
|
| 142 |
+
]
|
| 143 |
+
input_texts = queries + documents
|
| 144 |
+
|
| 145 |
+
tokenizer = AutoTokenizer.from_pretrained('Qwen/Qwen3-Embedding-0.6B', padding_side='left')
|
| 146 |
+
model = AutoModel.from_pretrained('Qwen/Qwen3-Embedding-0.6B')
|
| 147 |
+
|
| 148 |
+
# We recommend enabling flash_attention_2 for better acceleration and memory saving.
|
| 149 |
+
# model = AutoModel.from_pretrained('Qwen/Qwen3-Embedding-0.6B', attn_implementation="flash_attention_2", torch_dtype=torch.float16).cuda()
|
| 150 |
+
|
| 151 |
+
max_length = 8192
|
| 152 |
+
|
| 153 |
+
# Tokenize the input texts
|
| 154 |
+
batch_dict = tokenizer(
|
| 155 |
+
input_texts,
|
| 156 |
+
padding=True,
|
| 157 |
+
truncation=True,
|
| 158 |
+
max_length=max_length,
|
| 159 |
+
return_tensors="pt",
|
| 160 |
+
)
|
| 161 |
+
batch_dict.to(model.device)
|
| 162 |
+
outputs = model(**batch_dict)
|
| 163 |
+
embeddings = last_token_pool(outputs.last_hidden_state, batch_dict['attention_mask'])
|
| 164 |
+
|
| 165 |
+
# normalize embeddings
|
| 166 |
+
embeddings = F.normalize(embeddings, p=2, dim=1)
|
| 167 |
+
scores = (embeddings[:2] @ embeddings[2:].T)
|
| 168 |
+
print(scores.tolist())
|
| 169 |
+
# [[0.7645568251609802, 0.14142508804798126], [0.13549736142158508, 0.5999549627304077]]
|
| 170 |
+
```
|
| 171 |
+
|
| 172 |
+
### vLLM Usage
|
| 173 |
+
|
| 174 |
+
```python
|
| 175 |
+
# Requires vllm>=0.8.5
|
| 176 |
+
import torch
|
| 177 |
+
import vllm
|
| 178 |
+
from vllm import LLM
|
| 179 |
+
|
| 180 |
+
def get_detailed_instruct(task_description: str, query: str) -> str:
|
| 181 |
+
return f'Instruct: {task_description}\nQuery:{query}'
|
| 182 |
+
|
| 183 |
+
# Each query must come with a one-sentence instruction that describes the task
|
| 184 |
+
task = 'Given a web search query, retrieve relevant passages that answer the query'
|
| 185 |
+
|
| 186 |
+
queries = [
|
| 187 |
+
get_detailed_instruct(task, 'What is the capital of China?'),
|
| 188 |
+
get_detailed_instruct(task, 'Explain gravity')
|
| 189 |
+
]
|
| 190 |
+
# No need to add instruction for retrieval documents
|
| 191 |
+
documents = [
|
| 192 |
+
"The capital of China is Beijing.",
|
| 193 |
+
"Gravity is a force that attracts two bodies towards each other. It gives weight to physical objects and is responsible for the movement of planets around the sun."
|
| 194 |
+
]
|
| 195 |
+
input_texts = queries + documents
|
| 196 |
+
|
| 197 |
+
model = LLM(model="Qwen/Qwen3-Embedding-0.6B", task="embed")
|
| 198 |
+
|
| 199 |
+
outputs = model.embed(input_texts)
|
| 200 |
+
embeddings = torch.tensor([o.outputs.embedding for o in outputs])
|
| 201 |
+
scores = (embeddings[:2] @ embeddings[2:].T)
|
| 202 |
+
print(scores.tolist())
|
| 203 |
+
# [[0.7620252966880798, 0.14078938961029053], [0.1358368694782257, 0.6013815999031067]]
|
| 204 |
+
```
|
| 205 |
+
|
| 206 |
+
📌 **Tip**: We recommend that developers customize the `instruct` according to their specific scenarios, tasks, and languages. Our tests have shown that in most retrieval scenarios, not using an `instruct` on the query side can lead to a drop in retrieval performance by approximately 1% to 5%.
|
| 207 |
+
|
| 208 |
+
### Text Embeddings Inference (TEI) Usage
|
| 209 |
+
|
| 210 |
+
You can either run / deploy TEI on NVIDIA GPUs as:
|
| 211 |
+
|
| 212 |
+
```bash
|
| 213 |
+
docker run --gpus all -p 8080:80 -v hf_cache:/data --pull always ghcr.io/huggingface/text-embeddings-inference:cpu-1.7.2 --model-id Qwen/Qwen3-Embedding-0.6B --dtype float16
|
| 214 |
+
```
|
| 215 |
+
|
| 216 |
+
Or on CPU devices as:
|
| 217 |
+
|
| 218 |
+
```bash
|
| 219 |
+
docker run -p 8080:80 -v hf_cache:/data --pull always ghcr.io/huggingface/text-embeddings-inference:1.7.2 --model-id Qwen/Qwen3-Embedding-0.6B
|
| 220 |
+
```
|
| 221 |
+
|
| 222 |
+
And then, generate the embeddings sending a HTTP POST request as:
|
| 223 |
+
|
| 224 |
+
```bash
|
| 225 |
+
curl http://localhost:8080/embed \
|
| 226 |
+
-X POST \
|
| 227 |
+
-d '{"inputs": ["Instruct: Given a web search query, retrieve relevant passages that answer the query\nQuery: What is the capital of China?", "Instruct: Given a web search query, retrieve relevant passages that answer the query\nQuery: Explain gravity"]}' \
|
| 228 |
+
-H "Content-Type: application/json"
|
| 229 |
+
```
|
| 230 |
+
|
| 231 |
+
## Evaluation
|
| 232 |
+
|
| 233 |
+
### MTEB (Multilingual)
|
| 234 |
+
|
| 235 |
+
| Model | Size | Mean (Task) | Mean (Type) | Bitxt Mining | Class. | Clust. | Inst. Retri. | Multi. Class. | Pair. Class. | Rerank | Retri. | STS |
|
| 236 |
+
|----------------------------------|:-------:|:-------------:|:-------------:|:--------------:|:--------:|:--------:|:--------------:|:---------------:|:--------------:|:--------:|:--------:|:------:|
|
| 237 |
+
| NV-Embed-v2 | 7B | 56.29 | 49.58 | 57.84 | 57.29 | 40.80 | 1.04 | 18.63 | 78.94 | 63.82 | 56.72 | 71.10|
|
| 238 |
+
| GritLM-7B | 7B | 60.92 | 53.74 | 70.53 | 61.83 | 49.75 | 3.45 | 22.77 | 79.94 | 63.78 | 58.31 | 73.33|
|
| 239 |
+
| BGE-M3 | 0.6B | 59.56 | 52.18 | 79.11 | 60.35 | 40.88 | -3.11 | 20.1 | 80.76 | 62.79 | 54.60 | 74.12|
|
| 240 |
+
| multilingual-e5-large-instruct | 0.6B | 63.22 | 55.08 | 80.13 | 64.94 | 50.75 | -0.40 | 22.91 | 80.86 | 62.61 | 57.12 | 76.81|
|
| 241 |
+
| gte-Qwen2-1.5B-instruct | 1.5B | 59.45 | 52.69 | 62.51 | 58.32 | 52.05 | 0.74 | 24.02 | 81.58 | 62.58 | 60.78 | 71.61|
|
| 242 |
+
| gte-Qwen2-7b-Instruct | 7B | 62.51 | 55.93 | 73.92 | 61.55 | 52.77 | 4.94 | 25.48 | 85.13 | 65.55 | 60.08 | 73.98|
|
| 243 |
+
| text-embedding-3-large | - | 58.93 | 51.41 | 62.17 | 60.27 | 46.89 | -2.68 | 22.03 | 79.17 | 63.89 | 59.27 | 71.68|
|
| 244 |
+
| Cohere-embed-multilingual-v3.0 | - | 61.12 | 53.23 | 70.50 | 62.95 | 46.89 | -1.89 | 22.74 | 79.88 | 64.07 | 59.16 | 74.80|
|
| 245 |
+
| Gemini Embedding | - | 68.37 | 59.59 | 79.28 | 71.82 | 54.59 | 5.18 | **29.16** | 83.63 | 65.58 | 67.71 | 79.40|
|
| 246 |
+
| **Qwen3-Embedding-0.6B** | 0.6B | 64.33 | 56.00 | 72.22 | 66.83 | 52.33 | 5.09 | 24.59 | 80.83 | 61.41 | 64.64 | 76.17|
|
| 247 |
+
| **Qwen3-Embedding-4B** | 4B | 69.45 | 60.86 | 79.36 | 72.33 | 57.15 | **11.56** | 26.77 | 85.05 | 65.08 | 69.60 | 80.86|
|
| 248 |
+
| **Qwen3-Embedding-8B** | 8B | **70.58** | **61.69** | **80.89** | **74.00** | **57.65** | 10.06 | 28.66 | **86.40** | **65.63** | **70.88** | **81.08** |
|
| 249 |
+
|
| 250 |
+
> **Note**: For compared models, the scores are retrieved from MTEB online [leaderboard](https://huggingface.co/spaces/mteb/leaderboard) on May 24th, 2025.
|
| 251 |
+
|
| 252 |
+
### MTEB (Eng v2)
|
| 253 |
+
|
| 254 |
+
| MTEB English / Models | Param. | Mean(Task) | Mean(Type) | Class. | Clust. | Pair Class. | Rerank. | Retri. | STS | Summ. |
|
| 255 |
+
|--------------------------------|:--------:|:------------:|:------------:|:--------:|:--------:|:-------------:|:---------:|:--------:|:-------:|:-------:|
|
| 256 |
+
| multilingual-e5-large-instruct | 0.6B | 65.53 | 61.21 | 75.54 | 49.89 | 86.24 | 48.74 | 53.47 | 84.72 | 29.89 |
|
| 257 |
+
| NV-Embed-v2 | 7.8B | 69.81 | 65.00 | 87.19 | 47.66 | 88.69 | 49.61 | 62.84 | 83.82 | 35.21 |
|
| 258 |
+
| GritLM-7B | 7.2B | 67.07 | 63.22 | 81.25 | 50.82 | 87.29 | 49.59 | 54.95 | 83.03 | 35.65 |
|
| 259 |
+
| gte-Qwen2-1.5B-instruct | 1.5B | 67.20 | 63.26 | 85.84 | 53.54 | 87.52 | 49.25 | 50.25 | 82.51 | 33.94 |
|
| 260 |
+
| stella_en_1.5B_v5 | 1.5B | 69.43 | 65.32 | 89.38 | 57.06 | 88.02 | 50.19 | 52.42 | 83.27 | 36.91 |
|
| 261 |
+
| gte-Qwen2-7B-instruct | 7.6B | 70.72 | 65.77 | 88.52 | 58.97 | 85.9 | 50.47 | 58.09 | 82.69 | 35.74 |
|
| 262 |
+
| gemini-embedding-exp-03-07 | - | 73.3 | 67.67 | 90.05 | 59.39 | 87.7 | 48.59 | 64.35 | 85.29 | 38.28 |
|
| 263 |
+
| **Qwen3-Embedding-0.6B** | 0.6B | 70.70 | 64.88 | 85.76 | 54.05 | 84.37 | 48.18 | 61.83 | 86.57 | 33.43 |
|
| 264 |
+
| **Qwen3-Embedding-4B** | 4B | 74.60 | 68.10 | 89.84 | 57.51 | 87.01 | 50.76 | 68.46 | 88.72 | 34.39 |
|
| 265 |
+
| **Qwen3-Embedding-8B** | 8B | 75.22 | 68.71 | 90.43 | 58.57 | 87.52 | 51.56 | 69.44 | 88.58 | 34.83 |
|
| 266 |
+
|
| 267 |
+
### C-MTEB (MTEB Chinese)
|
| 268 |
+
|
| 269 |
+
| C-MTEB | Param. | Mean(Task) | Mean(Type) | Class. | Clust. | Pair Class. | Rerank. | Retr. | STS |
|
| 270 |
+
|------------------|--------|------------|------------|--------|--------|-------------|---------|-------|-------|
|
| 271 |
+
| multilingual-e5-large-instruct | 0.6B | 58.08 | 58.24 | 69.80 | 48.23 | 64.52 | 57.45 | 63.65 | 45.81 |
|
| 272 |
+
| bge-multilingual-gemma2 | 9B | 67.64 | 75.31 | 59.30 | 86.67 | 68.28 | 73.73 | 55.19 | - |
|
| 273 |
+
| gte-Qwen2-1.5B-instruct | 1.5B | 67.12 | 67.79 | 72.53 | 54.61 | 79.5 | 68.21 | 71.86 | 60.05 |
|
| 274 |
+
| gte-Qwen2-7B-instruct | 7.6B | 71.62 | 72.19 | 75.77 | 66.06 | 81.16 | 69.24 | 75.70 | 65.20 |
|
| 275 |
+
| ritrieve_zh_v1 | 0.3B | 72.71 | 73.85 | 76.88 | 66.5 | 85.98 | 72.86 | 76.97 | 63.92 |
|
| 276 |
+
| **Qwen3-Embedding-0.6B** | 0.6B | 66.33 | 67.45 | 71.40 | 68.74 | 76.42 | 62.58 | 71.03 | 54.52 |
|
| 277 |
+
| **Qwen3-Embedding-4B** | 4B | 72.27 | 73.51 | 75.46 | 77.89 | 83.34 | 66.05 | 77.03 | 61.26 |
|
| 278 |
+
| **Qwen3-Embedding-8B** | 8B | 73.84 | 75.00 | 76.97 | 80.08 | 84.23 | 66.99 | 78.21 | 63.53 |
|
| 279 |
+
|
| 280 |
+
|
| 281 |
+
## Citation
|
| 282 |
+
|
| 283 |
+
If you find our work helpful, feel free to give us a cite.
|
| 284 |
+
|
| 285 |
+
```
|
| 286 |
+
@article{qwen3embedding,
|
| 287 |
+
title={Qwen3 Embedding: Advancing Text Embedding and Reranking Through Foundation Models},
|
| 288 |
+
author={Zhang, Yanzhao and Li, Mingxin and Long, Dingkun and Zhang, Xin and Lin, Huan and Yang, Baosong and Xie, Pengjun and Yang, An and Liu, Dayiheng and Lin, Junyang and Huang, Fei and Zhou, Jingren},
|
| 289 |
+
journal={arXiv preprint arXiv:2506.05176},
|
| 290 |
+
year={2025}
|
| 291 |
+
}
|
| 292 |
+
```
|
models/Qwen3-Embedding-0.6B/config.json
ADDED
|
@@ -0,0 +1,30 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"architectures": [
|
| 3 |
+
"Qwen3ForCausalLM"
|
| 4 |
+
],
|
| 5 |
+
"attention_bias": false,
|
| 6 |
+
"attention_dropout": 0.0,
|
| 7 |
+
"bos_token_id": 151643,
|
| 8 |
+
"eos_token_id": 151643,
|
| 9 |
+
"head_dim": 128,
|
| 10 |
+
"hidden_act": "silu",
|
| 11 |
+
"hidden_size": 1024,
|
| 12 |
+
"initializer_range": 0.02,
|
| 13 |
+
"intermediate_size": 3072,
|
| 14 |
+
"max_position_embeddings": 32768,
|
| 15 |
+
"max_window_layers": 28,
|
| 16 |
+
"model_type": "qwen3",
|
| 17 |
+
"num_attention_heads": 16,
|
| 18 |
+
"num_hidden_layers": 28,
|
| 19 |
+
"num_key_value_heads": 8,
|
| 20 |
+
"rms_norm_eps": 1e-06,
|
| 21 |
+
"rope_scaling": null,
|
| 22 |
+
"rope_theta": 1000000,
|
| 23 |
+
"sliding_window": null,
|
| 24 |
+
"tie_word_embeddings": true,
|
| 25 |
+
"torch_dtype": "bfloat16",
|
| 26 |
+
"transformers_version": "4.51.3",
|
| 27 |
+
"use_cache": true,
|
| 28 |
+
"use_sliding_window": false,
|
| 29 |
+
"vocab_size": 151669
|
| 30 |
+
}
|
models/Qwen3-Embedding-0.6B/config_sentence_transformers.json
ADDED
|
@@ -0,0 +1,8 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"prompts": {
|
| 3 |
+
"query": "Instruct: Given a web search query, retrieve relevant passages that answer the query\nQuery:",
|
| 4 |
+
"document": ""
|
| 5 |
+
},
|
| 6 |
+
"default_prompt_name": null,
|
| 7 |
+
"similarity_fn_name": "cosine"
|
| 8 |
+
}
|
models/Qwen3-Embedding-0.6B/generation_config.json
ADDED
|
@@ -0,0 +1,6 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"bos_token_id": 151643,
|
| 3 |
+
"eos_token_id": 151643,
|
| 4 |
+
"max_new_tokens": 2048,
|
| 5 |
+
"transformers_version": "4.51.3"
|
| 6 |
+
}
|
models/Qwen3-Embedding-0.6B/merges.txt
ADDED
|
The diff for this file is too large to render.
See raw diff
|
|
|
models/Qwen3-Embedding-0.6B/model.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:0437e45c94563b09e13cb7a64478fc406947a93cb34a7e05870fc8dcd48e23fd
|
| 3 |
+
size 1191586416
|
models/Qwen3-Embedding-0.6B/modules.json
ADDED
|
@@ -0,0 +1,20 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
[
|
| 2 |
+
{
|
| 3 |
+
"idx": 0,
|
| 4 |
+
"name": "0",
|
| 5 |
+
"path": "",
|
| 6 |
+
"type": "sentence_transformers.models.Transformer"
|
| 7 |
+
},
|
| 8 |
+
{
|
| 9 |
+
"idx": 1,
|
| 10 |
+
"name": "1",
|
| 11 |
+
"path": "1_Pooling",
|
| 12 |
+
"type": "sentence_transformers.models.Pooling"
|
| 13 |
+
},
|
| 14 |
+
{
|
| 15 |
+
"idx": 2,
|
| 16 |
+
"name": "2",
|
| 17 |
+
"path": "2_Normalize",
|
| 18 |
+
"type": "sentence_transformers.models.Normalize"
|
| 19 |
+
}
|
| 20 |
+
]
|
models/Qwen3-Embedding-0.6B/tokenizer.json
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:def76fb086971c7867b829c23a26261e38d9d74e02139253b38aeb9df8b4b50a
|
| 3 |
+
size 11423705
|
models/Qwen3-Embedding-0.6B/tokenizer_config.json
ADDED
|
@@ -0,0 +1,240 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"add_bos_token": false,
|
| 3 |
+
"add_prefix_space": false,
|
| 4 |
+
"added_tokens_decoder": {
|
| 5 |
+
"151643": {
|
| 6 |
+
"content": "<|endoftext|>",
|
| 7 |
+
"lstrip": false,
|
| 8 |
+
"normalized": false,
|
| 9 |
+
"rstrip": false,
|
| 10 |
+
"single_word": false,
|
| 11 |
+
"special": true
|
| 12 |
+
},
|
| 13 |
+
"151644": {
|
| 14 |
+
"content": "<|im_start|>",
|
| 15 |
+
"lstrip": false,
|
| 16 |
+
"normalized": false,
|
| 17 |
+
"rstrip": false,
|
| 18 |
+
"single_word": false,
|
| 19 |
+
"special": true
|
| 20 |
+
},
|
| 21 |
+
"151645": {
|
| 22 |
+
"content": "<|im_end|>",
|
| 23 |
+
"lstrip": false,
|
| 24 |
+
"normalized": false,
|
| 25 |
+
"rstrip": false,
|
| 26 |
+
"single_word": false,
|
| 27 |
+
"special": true
|
| 28 |
+
},
|
| 29 |
+
"151646": {
|
| 30 |
+
"content": "<|object_ref_start|>",
|
| 31 |
+
"lstrip": false,
|
| 32 |
+
"normalized": false,
|
| 33 |
+
"rstrip": false,
|
| 34 |
+
"single_word": false,
|
| 35 |
+
"special": true
|
| 36 |
+
},
|
| 37 |
+
"151647": {
|
| 38 |
+
"content": "<|object_ref_end|>",
|
| 39 |
+
"lstrip": false,
|
| 40 |
+
"normalized": false,
|
| 41 |
+
"rstrip": false,
|
| 42 |
+
"single_word": false,
|
| 43 |
+
"special": true
|
| 44 |
+
},
|
| 45 |
+
"151648": {
|
| 46 |
+
"content": "<|box_start|>",
|
| 47 |
+
"lstrip": false,
|
| 48 |
+
"normalized": false,
|
| 49 |
+
"rstrip": false,
|
| 50 |
+
"single_word": false,
|
| 51 |
+
"special": true
|
| 52 |
+
},
|
| 53 |
+
"151649": {
|
| 54 |
+
"content": "<|box_end|>",
|
| 55 |
+
"lstrip": false,
|
| 56 |
+
"normalized": false,
|
| 57 |
+
"rstrip": false,
|
| 58 |
+
"single_word": false,
|
| 59 |
+
"special": true
|
| 60 |
+
},
|
| 61 |
+
"151650": {
|
| 62 |
+
"content": "<|quad_start|>",
|
| 63 |
+
"lstrip": false,
|
| 64 |
+
"normalized": false,
|
| 65 |
+
"rstrip": false,
|
| 66 |
+
"single_word": false,
|
| 67 |
+
"special": true
|
| 68 |
+
},
|
| 69 |
+
"151651": {
|
| 70 |
+
"content": "<|quad_end|>",
|
| 71 |
+
"lstrip": false,
|
| 72 |
+
"normalized": false,
|
| 73 |
+
"rstrip": false,
|
| 74 |
+
"single_word": false,
|
| 75 |
+
"special": true
|
| 76 |
+
},
|
| 77 |
+
"151652": {
|
| 78 |
+
"content": "<|vision_start|>",
|
| 79 |
+
"lstrip": false,
|
| 80 |
+
"normalized": false,
|
| 81 |
+
"rstrip": false,
|
| 82 |
+
"single_word": false,
|
| 83 |
+
"special": true
|
| 84 |
+
},
|
| 85 |
+
"151653": {
|
| 86 |
+
"content": "<|vision_end|>",
|
| 87 |
+
"lstrip": false,
|
| 88 |
+
"normalized": false,
|
| 89 |
+
"rstrip": false,
|
| 90 |
+
"single_word": false,
|
| 91 |
+
"special": true
|
| 92 |
+
},
|
| 93 |
+
"151654": {
|
| 94 |
+
"content": "<|vision_pad|>",
|
| 95 |
+
"lstrip": false,
|
| 96 |
+
"normalized": false,
|
| 97 |
+
"rstrip": false,
|
| 98 |
+
"single_word": false,
|
| 99 |
+
"special": true
|
| 100 |
+
},
|
| 101 |
+
"151655": {
|
| 102 |
+
"content": "<|image_pad|>",
|
| 103 |
+
"lstrip": false,
|
| 104 |
+
"normalized": false,
|
| 105 |
+
"rstrip": false,
|
| 106 |
+
"single_word": false,
|
| 107 |
+
"special": true
|
| 108 |
+
},
|
| 109 |
+
"151656": {
|
| 110 |
+
"content": "<|video_pad|>",
|
| 111 |
+
"lstrip": false,
|
| 112 |
+
"normalized": false,
|
| 113 |
+
"rstrip": false,
|
| 114 |
+
"single_word": false,
|
| 115 |
+
"special": true
|
| 116 |
+
},
|
| 117 |
+
"151657": {
|
| 118 |
+
"content": "<tool_call>",
|
| 119 |
+
"lstrip": false,
|
| 120 |
+
"normalized": false,
|
| 121 |
+
"rstrip": false,
|
| 122 |
+
"single_word": false,
|
| 123 |
+
"special": false
|
| 124 |
+
},
|
| 125 |
+
"151658": {
|
| 126 |
+
"content": "</tool_call>",
|
| 127 |
+
"lstrip": false,
|
| 128 |
+
"normalized": false,
|
| 129 |
+
"rstrip": false,
|
| 130 |
+
"single_word": false,
|
| 131 |
+
"special": false
|
| 132 |
+
},
|
| 133 |
+
"151659": {
|
| 134 |
+
"content": "<|fim_prefix|>",
|
| 135 |
+
"lstrip": false,
|
| 136 |
+
"normalized": false,
|
| 137 |
+
"rstrip": false,
|
| 138 |
+
"single_word": false,
|
| 139 |
+
"special": false
|
| 140 |
+
},
|
| 141 |
+
"151660": {
|
| 142 |
+
"content": "<|fim_middle|>",
|
| 143 |
+
"lstrip": false,
|
| 144 |
+
"normalized": false,
|
| 145 |
+
"rstrip": false,
|
| 146 |
+
"single_word": false,
|
| 147 |
+
"special": false
|
| 148 |
+
},
|
| 149 |
+
"151661": {
|
| 150 |
+
"content": "<|fim_suffix|>",
|
| 151 |
+
"lstrip": false,
|
| 152 |
+
"normalized": false,
|
| 153 |
+
"rstrip": false,
|
| 154 |
+
"single_word": false,
|
| 155 |
+
"special": false
|
| 156 |
+
},
|
| 157 |
+
"151662": {
|
| 158 |
+
"content": "<|fim_pad|>",
|
| 159 |
+
"lstrip": false,
|
| 160 |
+
"normalized": false,
|
| 161 |
+
"rstrip": false,
|
| 162 |
+
"single_word": false,
|
| 163 |
+
"special": false
|
| 164 |
+
},
|
| 165 |
+
"151663": {
|
| 166 |
+
"content": "<|repo_name|>",
|
| 167 |
+
"lstrip": false,
|
| 168 |
+
"normalized": false,
|
| 169 |
+
"rstrip": false,
|
| 170 |
+
"single_word": false,
|
| 171 |
+
"special": false
|
| 172 |
+
},
|
| 173 |
+
"151664": {
|
| 174 |
+
"content": "<|file_sep|>",
|
| 175 |
+
"lstrip": false,
|
| 176 |
+
"normalized": false,
|
| 177 |
+
"rstrip": false,
|
| 178 |
+
"single_word": false,
|
| 179 |
+
"special": false
|
| 180 |
+
},
|
| 181 |
+
"151665": {
|
| 182 |
+
"content": "<tool_response>",
|
| 183 |
+
"lstrip": false,
|
| 184 |
+
"normalized": false,
|
| 185 |
+
"rstrip": false,
|
| 186 |
+
"single_word": false,
|
| 187 |
+
"special": false
|
| 188 |
+
},
|
| 189 |
+
"151666": {
|
| 190 |
+
"content": "</tool_response>",
|
| 191 |
+
"lstrip": false,
|
| 192 |
+
"normalized": false,
|
| 193 |
+
"rstrip": false,
|
| 194 |
+
"single_word": false,
|
| 195 |
+
"special": false
|
| 196 |
+
},
|
| 197 |
+
"151667": {
|
| 198 |
+
"content": "<think>",
|
| 199 |
+
"lstrip": false,
|
| 200 |
+
"normalized": false,
|
| 201 |
+
"rstrip": false,
|
| 202 |
+
"single_word": false,
|
| 203 |
+
"special": false
|
| 204 |
+
},
|
| 205 |
+
"151668": {
|
| 206 |
+
"content": "</think>",
|
| 207 |
+
"lstrip": false,
|
| 208 |
+
"normalized": false,
|
| 209 |
+
"rstrip": false,
|
| 210 |
+
"single_word": false,
|
| 211 |
+
"special": false
|
| 212 |
+
}
|
| 213 |
+
},
|
| 214 |
+
"additional_special_tokens": [
|
| 215 |
+
"<|im_start|>",
|
| 216 |
+
"<|im_end|>",
|
| 217 |
+
"<|object_ref_start|>",
|
| 218 |
+
"<|object_ref_end|>",
|
| 219 |
+
"<|box_start|>",
|
| 220 |
+
"<|box_end|>",
|
| 221 |
+
"<|quad_start|>",
|
| 222 |
+
"<|quad_end|>",
|
| 223 |
+
"<|vision_start|>",
|
| 224 |
+
"<|vision_end|>",
|
| 225 |
+
"<|vision_pad|>",
|
| 226 |
+
"<|image_pad|>",
|
| 227 |
+
"<|video_pad|>"
|
| 228 |
+
],
|
| 229 |
+
"bos_token": null,
|
| 230 |
+
"chat_template": "{%- if tools %}\n {{- '<|im_start|>system\\n' }}\n {%- if messages[0].role == 'system' %}\n {{- messages[0].content + '\\n\\n' }}\n {%- endif %}\n {{- \"# Tools\\n\\nYou may call one or more functions to assist with the user query.\\n\\nYou are provided with function signatures within <tools></tools> XML tags:\\n<tools>\" }}\n {%- for tool in tools %}\n {{- \"\\n\" }}\n {{- tool | tojson }}\n {%- endfor %}\n {{- \"\\n</tools>\\n\\nFor each function call, return a json object with function name and arguments within <tool_call></tool_call> XML tags:\\n<tool_call>\\n{\\\"name\\\": <function-name>, \\\"arguments\\\": <args-json-object>}\\n</tool_call><|im_end|>\\n\" }}\n{%- else %}\n {%- if messages[0].role == 'system' %}\n {{- '<|im_start|>system\\n' + messages[0].content + '<|im_end|>\\n' }}\n {%- endif %}\n{%- endif %}\n{%- set ns = namespace(multi_step_tool=true, last_query_index=messages|length - 1) %}\n{%- for message in messages[::-1] %}\n {%- set index = (messages|length - 1) - loop.index0 %}\n {%- if ns.multi_step_tool and message.role == \"user\" and not(message.content.startswith('<tool_response>') and message.content.endswith('</tool_response>')) %}\n {%- set ns.multi_step_tool = false %}\n {%- set ns.last_query_index = index %}\n {%- endif %}\n{%- endfor %}\n{%- for message in messages %}\n {%- if (message.role == \"user\") or (message.role == \"system\" and not loop.first) %}\n {{- '<|im_start|>' + message.role + '\\n' + message.content + '<|im_end|>' + '\\n' }}\n {%- elif message.role == \"assistant\" %}\n {%- set content = message.content %}\n {%- set reasoning_content = '' %}\n {%- if message.reasoning_content is defined and message.reasoning_content is not none %}\n {%- set reasoning_content = message.reasoning_content %}\n {%- else %}\n {%- if '</think>' in message.content %}\n {%- set content = message.content.split('</think>')[-1].lstrip('\\n') %}\n {%- set reasoning_content = message.content.split('</think>')[0].rstrip('\\n').split('<think>')[-1].lstrip('\\n') %}\n {%- endif %}\n {%- endif %}\n {%- if loop.index0 > ns.last_query_index %}\n {%- if loop.last or (not loop.last and reasoning_content) %}\n {{- '<|im_start|>' + message.role + '\\n<think>\\n' + reasoning_content.strip('\\n') + '\\n</think>\\n\\n' + content.lstrip('\\n') }}\n {%- else %}\n {{- '<|im_start|>' + message.role + '\\n' + content }}\n {%- endif %}\n {%- else %}\n {{- '<|im_start|>' + message.role + '\\n' + content }}\n {%- endif %}\n {%- if message.tool_calls %}\n {%- for tool_call in message.tool_calls %}\n {%- if (loop.first and content) or (not loop.first) %}\n {{- '\\n' }}\n {%- endif %}\n {%- if tool_call.function %}\n {%- set tool_call = tool_call.function %}\n {%- endif %}\n {{- '<tool_call>\\n{\"name\": \"' }}\n {{- tool_call.name }}\n {{- '\", \"arguments\": ' }}\n {%- if tool_call.arguments is string %}\n {{- tool_call.arguments }}\n {%- else %}\n {{- tool_call.arguments | tojson }}\n {%- endif %}\n {{- '}\\n</tool_call>' }}\n {%- endfor %}\n {%- endif %}\n {{- '<|im_end|>\\n' }}\n {%- elif message.role == \"tool\" %}\n {%- if loop.first or (messages[loop.index0 - 1].role != \"tool\") %}\n {{- '<|im_start|>user' }}\n {%- endif %}\n {{- '\\n<tool_response>\\n' }}\n {{- message.content }}\n {{- '\\n</tool_response>' }}\n {%- if loop.last or (messages[loop.index0 + 1].role != \"tool\") %}\n {{- '<|im_end|>\\n' }}\n {%- endif %}\n {%- endif %}\n{%- endfor %}\n{%- if add_generation_prompt %}\n {{- '<|im_start|>assistant\\n' }}\n {%- if enable_thinking is defined and enable_thinking is false %}\n {{- '<think>\\n\\n</think>\\n\\n' }}\n {%- endif %}\n{%- endif %}",
|
| 231 |
+
"clean_up_tokenization_spaces": false,
|
| 232 |
+
"eos_token": "<|im_end|>",
|
| 233 |
+
"errors": "replace",
|
| 234 |
+
"extra_special_tokens": {},
|
| 235 |
+
"model_max_length": 131072,
|
| 236 |
+
"pad_token": "<|endoftext|>",
|
| 237 |
+
"split_special_tokens": false,
|
| 238 |
+
"tokenizer_class": "Qwen2Tokenizer",
|
| 239 |
+
"unk_token": null
|
| 240 |
+
}
|
models/Qwen3-Embedding-0.6B/vocab.json
ADDED
|
The diff for this file is too large to render.
See raw diff
|
|
|