



Commit ·
c408afd
0
Parent(s):
Duplicate from microsoft/conditional-detr-resnet-50
Browse filesCo-authored-by: Depu Meng <DepuMeng@users.noreply.huggingface.co>
- .gitattributes +33 -0
- README.md +92 -0
- config.json +217 -0
- model.safetensors +3 -0
- preprocessor_config.json +17 -0
- pytorch_model.bin +3 -0
.gitattributes
ADDED
|
@@ -0,0 +1,33 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
*.7z filter=lfs diff=lfs merge=lfs -text
|
| 2 |
+
*.arrow filter=lfs diff=lfs merge=lfs -text
|
| 3 |
+
*.bin filter=lfs diff=lfs merge=lfs -text
|
| 4 |
+
*.bz2 filter=lfs diff=lfs merge=lfs -text
|
| 5 |
+
*.ftz filter=lfs diff=lfs merge=lfs -text
|
| 6 |
+
*.gz filter=lfs diff=lfs merge=lfs -text
|
| 7 |
+
*.h5 filter=lfs diff=lfs merge=lfs -text
|
| 8 |
+
*.joblib filter=lfs diff=lfs merge=lfs -text
|
| 9 |
+
*.lfs.* filter=lfs diff=lfs merge=lfs -text
|
| 10 |
+
*.mlmodel filter=lfs diff=lfs merge=lfs -text
|
| 11 |
+
*.model filter=lfs diff=lfs merge=lfs -text
|
| 12 |
+
*.msgpack filter=lfs diff=lfs merge=lfs -text
|
| 13 |
+
*.npy filter=lfs diff=lfs merge=lfs -text
|
| 14 |
+
*.npz filter=lfs diff=lfs merge=lfs -text
|
| 15 |
+
*.onnx filter=lfs diff=lfs merge=lfs -text
|
| 16 |
+
*.ot filter=lfs diff=lfs merge=lfs -text
|
| 17 |
+
*.parquet filter=lfs diff=lfs merge=lfs -text
|
| 18 |
+
*.pb filter=lfs diff=lfs merge=lfs -text
|
| 19 |
+
*.pickle filter=lfs diff=lfs merge=lfs -text
|
| 20 |
+
*.pkl filter=lfs diff=lfs merge=lfs -text
|
| 21 |
+
*.pt filter=lfs diff=lfs merge=lfs -text
|
| 22 |
+
*.pth filter=lfs diff=lfs merge=lfs -text
|
| 23 |
+
*.rar filter=lfs diff=lfs merge=lfs -text
|
| 24 |
+
saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
| 25 |
+
*.tar.* filter=lfs diff=lfs merge=lfs -text
|
| 26 |
+
*.tflite filter=lfs diff=lfs merge=lfs -text
|
| 27 |
+
*.tgz filter=lfs diff=lfs merge=lfs -text
|
| 28 |
+
*.wasm filter=lfs diff=lfs merge=lfs -text
|
| 29 |
+
*.xz filter=lfs diff=lfs merge=lfs -text
|
| 30 |
+
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 31 |
+
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 32 |
+
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
| 33 |
+
model.safetensors filter=lfs diff=lfs merge=lfs -text
|
README.md
ADDED
|
@@ -0,0 +1,92 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
---
|
| 2 |
+
license: apache-2.0
|
| 3 |
+
tags:
|
| 4 |
+
- object-detection
|
| 5 |
+
- vision
|
| 6 |
+
datasets:
|
| 7 |
+
- coco
|
| 8 |
+
widget:
|
| 9 |
+
- src: https://huggingface.co/datasets/mishig/sample_images/resolve/main/savanna.jpg
|
| 10 |
+
example_title: Savanna
|
| 11 |
+
- src: https://huggingface.co/datasets/mishig/sample_images/resolve/main/football-match.jpg
|
| 12 |
+
example_title: Football Match
|
| 13 |
+
- src: https://huggingface.co/datasets/mishig/sample_images/resolve/main/airport.jpg
|
| 14 |
+
example_title: Airport
|
| 15 |
+
---
|
| 16 |
+
|
| 17 |
+
# Conditional DETR model with ResNet-50 backbone
|
| 18 |
+
|
| 19 |
+
Conditional DEtection TRansformer (DETR) model trained end-to-end on COCO 2017 object detection (118k annotated images). It was introduced in the paper [Conditional DETR for Fast Training Convergence](https://arxiv.org/abs/2108.06152) by Meng et al. and first released in [this repository](https://github.com/Atten4Vis/ConditionalDETR).
|
| 20 |
+
|
| 21 |
+
|
| 22 |
+
## Model description
|
| 23 |
+
|
| 24 |
+
The recently-developed DETR approach applies the transformer encoder and decoder architecture to object detection and achieves promising performance. In this paper, we handle the critical issue, slow training convergence, and present a conditional cross-attention mechanism for fast DETR training. Our approach is motivated by that the cross-attention in DETR relies highly on the content embeddings for localizing the four extremities and predicting the box, which increases the need for high-quality content embeddings and thus the training difficulty. Our approach, named conditional DETR, learns a conditional spatial query from the decoder embedding for decoder multi-head cross-attention. The benefit is that through the conditional spatial query, each cross-attention head is able to attend to a band containing a distinct region, e.g., one object extremity or a region inside the object box. This narrows down the spatial range for localizing the distinct regions for object classification and box regression, thus relaxing the dependence on the content embeddings and easing the training. Empirical results show that conditional DETR converges 6.7× faster for the backbones R50 and R101 and 10× faster for stronger backbones DC5-R50 and DC5-R101.
|
| 25 |
+
|
| 26 |
+
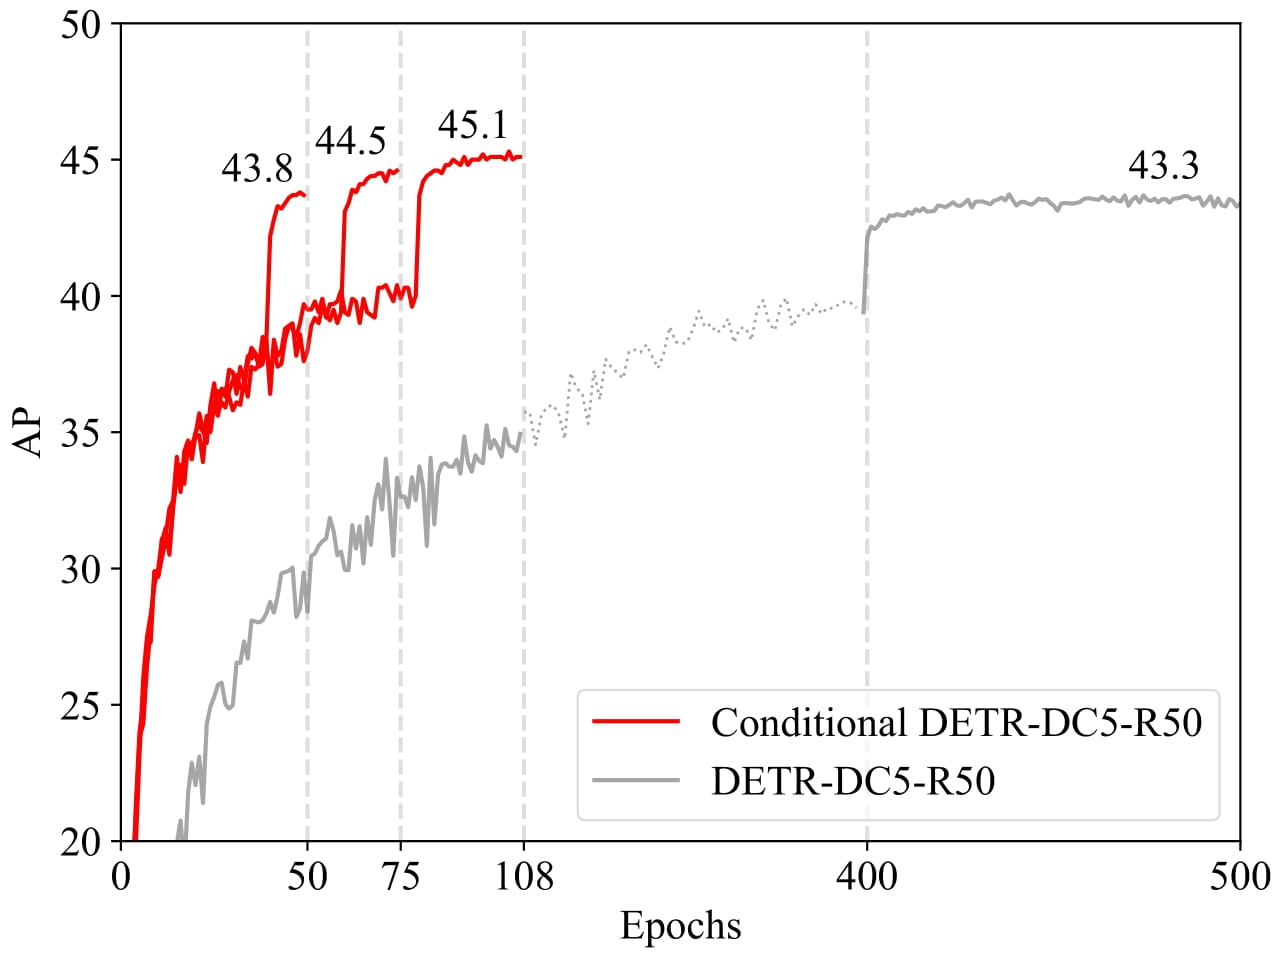
|
| 27 |
+
|
| 28 |
+
## Intended uses & limitations
|
| 29 |
+
|
| 30 |
+
You can use the raw model for object detection. See the [model hub](https://huggingface.co/models?search=microsoft/conditional-detr) to look for all available Conditional DETR models.
|
| 31 |
+
|
| 32 |
+
### How to use
|
| 33 |
+
|
| 34 |
+
Here is how to use this model:
|
| 35 |
+
|
| 36 |
+
```python
|
| 37 |
+
from transformers import AutoImageProcessor, ConditionalDetrForObjectDetection
|
| 38 |
+
import torch
|
| 39 |
+
from PIL import Image
|
| 40 |
+
import requests
|
| 41 |
+
|
| 42 |
+
url = "http://images.cocodataset.org/val2017/000000039769.jpg"
|
| 43 |
+
image = Image.open(requests.get(url, stream=True).raw)
|
| 44 |
+
|
| 45 |
+
processor = AutoImageProcessor.from_pretrained("microsoft/conditional-detr-resnet-50")
|
| 46 |
+
model = ConditionalDetrForObjectDetection.from_pretrained("microsoft/conditional-detr-resnet-50")
|
| 47 |
+
|
| 48 |
+
inputs = processor(images=image, return_tensors="pt")
|
| 49 |
+
outputs = model(**inputs)
|
| 50 |
+
|
| 51 |
+
# convert outputs (bounding boxes and class logits) to COCO API
|
| 52 |
+
# let's only keep detections with score > 0.7
|
| 53 |
+
target_sizes = torch.tensor([image.size[::-1]])
|
| 54 |
+
results = processor.post_process_object_detection(outputs, target_sizes=target_sizes, threshold=0.7)[0]
|
| 55 |
+
|
| 56 |
+
for score, label, box in zip(results["scores"], results["labels"], results["boxes"]):
|
| 57 |
+
box = [round(i, 2) for i in box.tolist()]
|
| 58 |
+
print(
|
| 59 |
+
f"Detected {model.config.id2label[label.item()]} with confidence "
|
| 60 |
+
f"{round(score.item(), 3)} at location {box}"
|
| 61 |
+
)
|
| 62 |
+
```
|
| 63 |
+
This should output:
|
| 64 |
+
```
|
| 65 |
+
Detected remote with confidence 0.833 at location [38.31, 72.1, 177.63, 118.45]
|
| 66 |
+
Detected cat with confidence 0.831 at location [9.2, 51.38, 321.13, 469.0]
|
| 67 |
+
Detected cat with confidence 0.804 at location [340.3, 16.85, 642.93, 370.95]
|
| 68 |
+
```
|
| 69 |
+
|
| 70 |
+
Currently, both the feature extractor and model support PyTorch.
|
| 71 |
+
|
| 72 |
+
## Training data
|
| 73 |
+
|
| 74 |
+
The Conditional DETR model was trained on [COCO 2017 object detection](https://cocodataset.org/#download), a dataset consisting of 118k/5k annotated images for training/validation respectively.
|
| 75 |
+
|
| 76 |
+
### BibTeX entry and citation info
|
| 77 |
+
|
| 78 |
+
```bibtex
|
| 79 |
+
@inproceedings{MengCFZLYS021,
|
| 80 |
+
author = {Depu Meng and
|
| 81 |
+
Xiaokang Chen and
|
| 82 |
+
Zejia Fan and
|
| 83 |
+
Gang Zeng and
|
| 84 |
+
Houqiang Li and
|
| 85 |
+
Yuhui Yuan and
|
| 86 |
+
Lei Sun and
|
| 87 |
+
Jingdong Wang},
|
| 88 |
+
title = {Conditional {DETR} for Fast Training Convergence},
|
| 89 |
+
booktitle = {2021 {IEEE/CVF} International Conference on Computer Vision, {ICCV}
|
| 90 |
+
2021, Montreal, QC, Canada, October 10-17, 2021},
|
| 91 |
+
}
|
| 92 |
+
```
|
config.json
ADDED
|
@@ -0,0 +1,217 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"activation_dropout": 0.0,
|
| 3 |
+
"activation_function": "relu",
|
| 4 |
+
"architectures": [
|
| 5 |
+
"ConditionalDETRForObjectDetection"
|
| 6 |
+
],
|
| 7 |
+
"attention_dropout": 0.0,
|
| 8 |
+
"auxiliary_loss": false,
|
| 9 |
+
"backbone": "resnet50",
|
| 10 |
+
"bbox_cost": 5,
|
| 11 |
+
"bbox_loss_coefficient": 5,
|
| 12 |
+
"class_cost": 2,
|
| 13 |
+
"cls_loss_coefficient": 2,
|
| 14 |
+
"d_model": 256,
|
| 15 |
+
"decoder_attention_heads": 8,
|
| 16 |
+
"decoder_ffn_dim": 2048,
|
| 17 |
+
"decoder_layerdrop": 0.0,
|
| 18 |
+
"decoder_layers": 6,
|
| 19 |
+
"dice_loss_coefficient": 1,
|
| 20 |
+
"dilation": false,
|
| 21 |
+
"dropout": 0.1,
|
| 22 |
+
"encoder_attention_heads": 8,
|
| 23 |
+
"encoder_ffn_dim": 2048,
|
| 24 |
+
"encoder_layerdrop": 0.0,
|
| 25 |
+
"encoder_layers": 6,
|
| 26 |
+
"focal_alpha": 0.25,
|
| 27 |
+
"giou_cost": 2,
|
| 28 |
+
"giou_loss_coefficient": 2,
|
| 29 |
+
"id2label": {
|
| 30 |
+
"0": "N/A",
|
| 31 |
+
"1": "person",
|
| 32 |
+
"2": "bicycle",
|
| 33 |
+
"3": "car",
|
| 34 |
+
"4": "motorcycle",
|
| 35 |
+
"5": "airplane",
|
| 36 |
+
"6": "bus",
|
| 37 |
+
"7": "train",
|
| 38 |
+
"8": "truck",
|
| 39 |
+
"9": "boat",
|
| 40 |
+
"10": "traffic light",
|
| 41 |
+
"11": "fire hydrant",
|
| 42 |
+
"12": "N/A",
|
| 43 |
+
"13": "stop sign",
|
| 44 |
+
"14": "parking meter",
|
| 45 |
+
"15": "bench",
|
| 46 |
+
"16": "bird",
|
| 47 |
+
"17": "cat",
|
| 48 |
+
"18": "dog",
|
| 49 |
+
"19": "horse",
|
| 50 |
+
"20": "sheep",
|
| 51 |
+
"21": "cow",
|
| 52 |
+
"22": "elephant",
|
| 53 |
+
"23": "bear",
|
| 54 |
+
"24": "zebra",
|
| 55 |
+
"25": "giraffe",
|
| 56 |
+
"26": "N/A",
|
| 57 |
+
"27": "backpack",
|
| 58 |
+
"28": "umbrella",
|
| 59 |
+
"29": "N/A",
|
| 60 |
+
"30": "N/A",
|
| 61 |
+
"31": "handbag",
|
| 62 |
+
"32": "tie",
|
| 63 |
+
"33": "suitcase",
|
| 64 |
+
"34": "frisbee",
|
| 65 |
+
"35": "skis",
|
| 66 |
+
"36": "snowboard",
|
| 67 |
+
"37": "sports ball",
|
| 68 |
+
"38": "kite",
|
| 69 |
+
"39": "baseball bat",
|
| 70 |
+
"40": "baseball glove",
|
| 71 |
+
"41": "skateboard",
|
| 72 |
+
"42": "surfboard",
|
| 73 |
+
"43": "tennis racket",
|
| 74 |
+
"44": "bottle",
|
| 75 |
+
"45": "N/A",
|
| 76 |
+
"46": "wine glass",
|
| 77 |
+
"47": "cup",
|
| 78 |
+
"48": "fork",
|
| 79 |
+
"49": "knife",
|
| 80 |
+
"50": "spoon",
|
| 81 |
+
"51": "bowl",
|
| 82 |
+
"52": "banana",
|
| 83 |
+
"53": "apple",
|
| 84 |
+
"54": "sandwich",
|
| 85 |
+
"55": "orange",
|
| 86 |
+
"56": "broccoli",
|
| 87 |
+
"57": "carrot",
|
| 88 |
+
"58": "hot dog",
|
| 89 |
+
"59": "pizza",
|
| 90 |
+
"60": "donut",
|
| 91 |
+
"61": "cake",
|
| 92 |
+
"62": "chair",
|
| 93 |
+
"63": "couch",
|
| 94 |
+
"64": "potted plant",
|
| 95 |
+
"65": "bed",
|
| 96 |
+
"66": "N/A",
|
| 97 |
+
"67": "dining table",
|
| 98 |
+
"68": "N/A",
|
| 99 |
+
"69": "N/A",
|
| 100 |
+
"70": "toilet",
|
| 101 |
+
"71": "N/A",
|
| 102 |
+
"72": "tv",
|
| 103 |
+
"73": "laptop",
|
| 104 |
+
"74": "mouse",
|
| 105 |
+
"75": "remote",
|
| 106 |
+
"76": "keyboard",
|
| 107 |
+
"77": "cell phone",
|
| 108 |
+
"78": "microwave",
|
| 109 |
+
"79": "oven",
|
| 110 |
+
"80": "toaster",
|
| 111 |
+
"81": "sink",
|
| 112 |
+
"82": "refrigerator",
|
| 113 |
+
"83": "N/A",
|
| 114 |
+
"84": "book",
|
| 115 |
+
"85": "clock",
|
| 116 |
+
"86": "vase",
|
| 117 |
+
"87": "scissors",
|
| 118 |
+
"88": "teddy bear",
|
| 119 |
+
"89": "hair drier",
|
| 120 |
+
"90": "toothbrush"
|
| 121 |
+
},
|
| 122 |
+
"init_std": 0.02,
|
| 123 |
+
"init_xavier_std": 1.0,
|
| 124 |
+
"is_encoder_decoder": true,
|
| 125 |
+
"label2id": {
|
| 126 |
+
"N/A": 83,
|
| 127 |
+
"airplane": 5,
|
| 128 |
+
"apple": 53,
|
| 129 |
+
"backpack": 27,
|
| 130 |
+
"banana": 52,
|
| 131 |
+
"baseball bat": 39,
|
| 132 |
+
"baseball glove": 40,
|
| 133 |
+
"bear": 23,
|
| 134 |
+
"bed": 65,
|
| 135 |
+
"bench": 15,
|
| 136 |
+
"bicycle": 2,
|
| 137 |
+
"bird": 16,
|
| 138 |
+
"boat": 9,
|
| 139 |
+
"book": 84,
|
| 140 |
+
"bottle": 44,
|
| 141 |
+
"bowl": 51,
|
| 142 |
+
"broccoli": 56,
|
| 143 |
+
"bus": 6,
|
| 144 |
+
"cake": 61,
|
| 145 |
+
"car": 3,
|
| 146 |
+
"carrot": 57,
|
| 147 |
+
"cat": 17,
|
| 148 |
+
"cell phone": 77,
|
| 149 |
+
"chair": 62,
|
| 150 |
+
"clock": 85,
|
| 151 |
+
"couch": 63,
|
| 152 |
+
"cow": 21,
|
| 153 |
+
"cup": 47,
|
| 154 |
+
"dining table": 67,
|
| 155 |
+
"dog": 18,
|
| 156 |
+
"donut": 60,
|
| 157 |
+
"elephant": 22,
|
| 158 |
+
"fire hydrant": 11,
|
| 159 |
+
"fork": 48,
|
| 160 |
+
"frisbee": 34,
|
| 161 |
+
"giraffe": 25,
|
| 162 |
+
"hair drier": 89,
|
| 163 |
+
"handbag": 31,
|
| 164 |
+
"horse": 19,
|
| 165 |
+
"hot dog": 58,
|
| 166 |
+
"keyboard": 76,
|
| 167 |
+
"kite": 38,
|
| 168 |
+
"knife": 49,
|
| 169 |
+
"laptop": 73,
|
| 170 |
+
"microwave": 78,
|
| 171 |
+
"motorcycle": 4,
|
| 172 |
+
"mouse": 74,
|
| 173 |
+
"orange": 55,
|
| 174 |
+
"oven": 79,
|
| 175 |
+
"parking meter": 14,
|
| 176 |
+
"person": 1,
|
| 177 |
+
"pizza": 59,
|
| 178 |
+
"potted plant": 64,
|
| 179 |
+
"refrigerator": 82,
|
| 180 |
+
"remote": 75,
|
| 181 |
+
"sandwich": 54,
|
| 182 |
+
"scissors": 87,
|
| 183 |
+
"sheep": 20,
|
| 184 |
+
"sink": 81,
|
| 185 |
+
"skateboard": 41,
|
| 186 |
+
"skis": 35,
|
| 187 |
+
"snowboard": 36,
|
| 188 |
+
"spoon": 50,
|
| 189 |
+
"sports ball": 37,
|
| 190 |
+
"stop sign": 13,
|
| 191 |
+
"suitcase": 33,
|
| 192 |
+
"surfboard": 42,
|
| 193 |
+
"teddy bear": 88,
|
| 194 |
+
"tennis racket": 43,
|
| 195 |
+
"tie": 32,
|
| 196 |
+
"toaster": 80,
|
| 197 |
+
"toilet": 70,
|
| 198 |
+
"toothbrush": 90,
|
| 199 |
+
"traffic light": 10,
|
| 200 |
+
"train": 7,
|
| 201 |
+
"truck": 8,
|
| 202 |
+
"tv": 72,
|
| 203 |
+
"umbrella": 28,
|
| 204 |
+
"vase": 86,
|
| 205 |
+
"wine glass": 46,
|
| 206 |
+
"zebra": 24
|
| 207 |
+
},
|
| 208 |
+
"mask_loss_coefficient": 1,
|
| 209 |
+
"max_position_embeddings": 1024,
|
| 210 |
+
"model_type": "conditional_detr",
|
| 211 |
+
"num_hidden_layers": 6,
|
| 212 |
+
"num_queries": 300,
|
| 213 |
+
"position_embedding_type": "sine",
|
| 214 |
+
"scale_embedding": false,
|
| 215 |
+
"torch_dtype": "float32",
|
| 216 |
+
"transformers_version": "4.22.0.dev0"
|
| 217 |
+
}
|
model.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:e8553b4fa875b7d67d15609e140f969563742b4ee17b75d9095612a8f00d3ed8
|
| 3 |
+
size 174168748
|
preprocessor_config.json
ADDED
|
@@ -0,0 +1,17 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"do_normalize": true,
|
| 3 |
+
"do_resize": true,
|
| 4 |
+
"image_processor_type": "ConditionalDetrImageProcessor",
|
| 5 |
+
"format": "coco_detection",
|
| 6 |
+
"image_mean": [
|
| 7 |
+
0.485,
|
| 8 |
+
0.456,
|
| 9 |
+
0.406
|
| 10 |
+
],
|
| 11 |
+
"image_std": [
|
| 12 |
+
0.229,
|
| 13 |
+
0.224,
|
| 14 |
+
0.225
|
| 15 |
+
],
|
| 16 |
+
"size": {"shortest_edge": 800, "longest_edge": 1333}
|
| 17 |
+
}
|
pytorch_model.bin
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:2b589a660bb30e561c780dc8840da90a5e61edb8d9a3988fd7f367cc414dc67a
|
| 3 |
+
size 174290209
|