
File size: 4,181 Bytes
61cdabd 18dcaa0 629d1d2 18dcaa0 4927703 18dcaa0 61cdabd 18dcaa0 474c4e3 18dcaa0 474c4e3 18dcaa0 474c4e3 18dcaa0 61cdabd 18dcaa0 61cdabd 18dcaa0 61cdabd 18dcaa0 61cdabd 629d1d2 61cdabd | 1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 58 59 60 61 62 63 64 65 66 67 68 69 70 71 72 73 74 75 76 77 78 79 80 81 82 83 84 85 86 87 88 89 90 91 92 93 94 95 96 97 98 99 100 101 102 103 104 105 106 107 108 109 110 111 112 113 114 115 116 117 118 119 | ---
license: mit
library_name: assayloop
tags:
- biology
- genomics
- crispr
- active-learning
- drug-discovery
pipeline_tag: other
---
# AssayFormer
[Website](https://genentech.github.io/AssayLoop) | [Models and Data](https://huggingface.co/collections/Genentech/assaybench) | [Paper](https://arxiv.org/abs/2609.11877) | [](https://pypi.org/project/assaybench/)
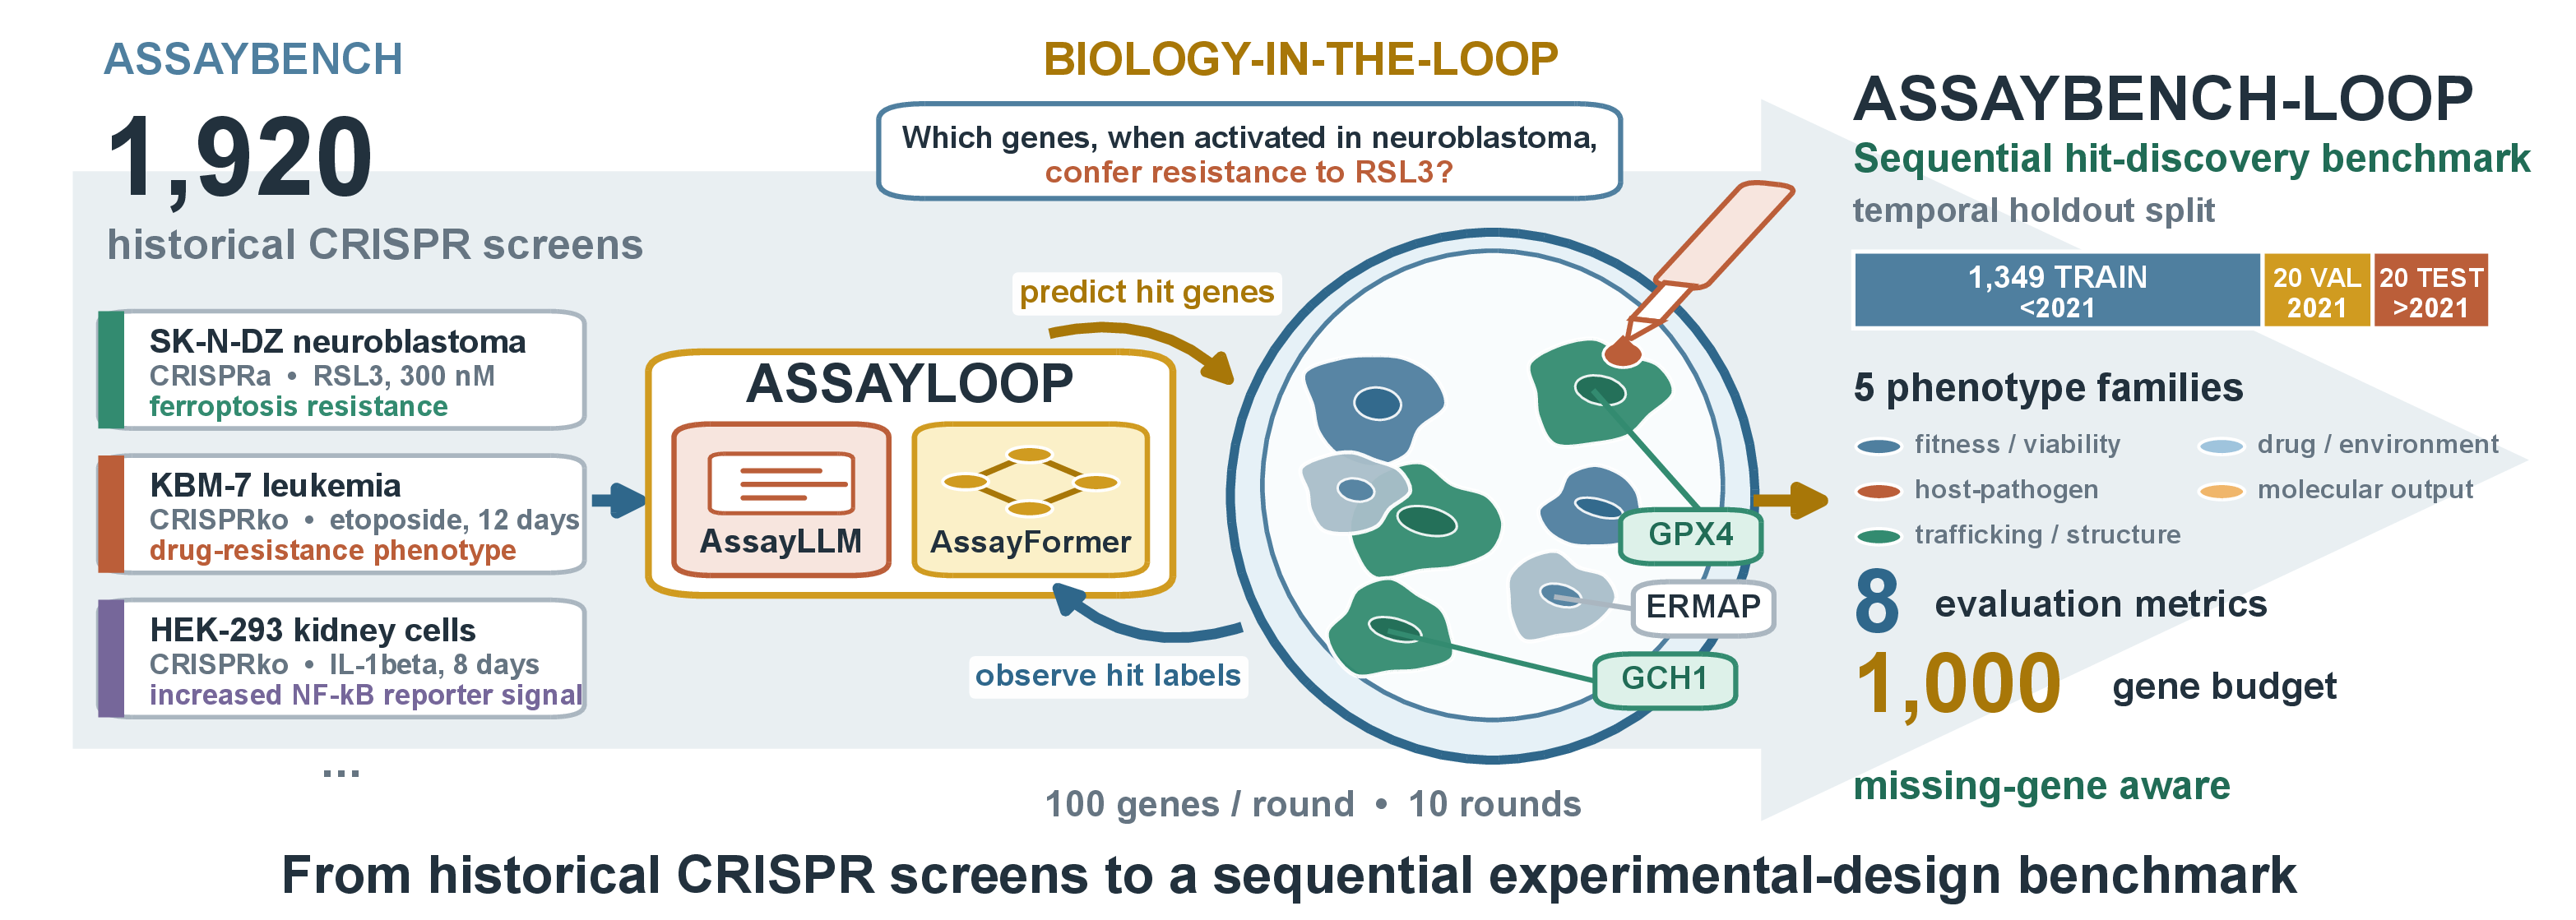
The amortized gene ranker from **AssayLoop**: *Biology-in-the-loop: Amortized
Adaptive Hit Discovery in CRISPR Screens*. Given a screen description and the
hit labels revealed so far, it scores every gene in a 24,217-gene vocabulary and
proposes the next batch to assay. In the paper, a 21,147 gene subset was used.
## Usage
```python
from huggingface_hub import snapshot_download
from assayloop.models.amortized_ranker import AmortizedRankerModel
ckpt = snapshot_download("Genentech/assayformer")
model = AmortizedRankerModel(checkpoint=ckpt, ckpt_file="model_last.pt")
```
Note the explicit `ckpt_file`: the loader defaults to `model.pt`, which is not
in this repository.
Then run it on a held-out screen and score the trajectory:
```python
from assaybench import SequentialLoop, enrichment_factor, gene_universe, load_screens
from assayloop.acquisitions.greedy_from_model import GreedyFromModel
from assayloop.tasks import AssayBenchGeneBatchTask
screens = load_screens("assayloop-test") # the paper's 20-screen test set
universe = gene_universe(screens) # the f2 pool, 21,147 genes
screen = screens[0]
task = AssayBenchGeneBatchTask(screen, universe_genes=universe)
run = SequentialLoop(task, model, GreedyFromModel(), metrics=[], batch_size=100).run(n_steps=10)
picked = [g for step in run.history for g in step.acquired_batch]
hits = [g for g, h in zip(screen.genes, screen.hits) if h]
print(enrichment_factor(picked, screen.genes, hits, universe=universe, budget=1000)) # 7.61 on U_1733_merged
```
## Results
| metric | value |
|---|---|
| Enrichment factor (EF, domain-adjusted) | 4.83 |
| Fraction of hits recovered at budget 1000 | 0.232 |
| Domain-adjusted nAUC | 0.172 |
| Picks outside the screen's library | 0.100 |
| DepMap common-essential fraction | 0.407 |
| Effective pathways EP-B / EP-S / EP-D | 19.3 / 46.7 / 65.0 |
## Files
| file | what |
|---|---|
| `model_last.pt` | weights — 5,033,117 parameters, the final GRPO epoch |
| `config.json` | architecture and RL hyperparameters |
| `vocab.json` | the 24,217-entry gene vocabulary (index 0 is `<unk>`) |
`model_last.pt` is the checkpoint the paper reports. If you want the gene embedding table on its
own it is `state_dict["gene_emb.weight"]`, shape (24217, 10).
## Architecture
A 3-layer transformer encoder over a sequence of observed (gene, label) pairs
plus the screen description, scoring candidates by dot product against a learned
gene embedding.
| | |
|---|---|
| encoder | 3 layers, `d_model` 384, 2 heads, FFN 1024, no dropout |
| gene embeddings | 24,217 × 10, initialised from a K=10 BPMF fit |
| description | 1536-d, projected to 384 |
| context | up to 1024 observations |
**The description input is a precomputed embedding, not text.** The model
expects a 1536-d vector from OpenAI `text-embedding-3-small`. The
repository ships the screen-description embeddings for the benchmark screens, so
you only need an embedding backend for screens of your own.
## Citation
```bibtex
@article{edwards2026biologyloop,
title={Biology-in-the-loop: Amortized Adaptive Hit Discovery in CRISPR Screens},
author={Edwards, Carl and De Brouwer, Edward and Li, Xiner and Lee, Namkyeong and
Hajiramezanali, Ehsan and Biton, Anne and Mostafavi, Sara and Scalia, Gabriele},
journal={arXiv preprint arXiv:2609.11877},
url={https://arxiv.org/abs/2609.11877},
year={2026}
}
```
Licensed MIT, © 2026 Genentech, Inc.
|