


File size: 9,304 Bytes
5c4d819 | 1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 58 59 60 61 62 63 64 65 66 67 68 69 70 71 72 73 74 75 76 77 78 79 80 81 82 83 84 85 86 87 88 89 90 91 92 93 94 95 96 97 98 99 100 101 102 103 104 105 106 107 108 109 110 111 112 113 114 115 116 117 118 119 120 121 122 123 124 125 126 127 128 129 130 131 132 133 134 135 136 137 138 139 140 141 142 143 144 145 146 147 148 149 150 151 152 153 154 155 156 157 158 159 160 161 162 163 164 165 166 167 168 169 170 171 172 173 174 175 176 177 178 179 180 181 182 183 184 185 186 187 188 189 190 191 192 193 194 195 196 197 198 199 200 201 202 203 204 205 206 207 208 209 210 211 212 213 214 215 216 217 218 219 220 221 222 223 224 225 226 227 228 229 230 231 232 233 234 235 236 237 238 239 240 241 242 243 244 245 246 247 248 249 250 251 252 253 254 255 256 257 258 | ---
license: apache-2.0
language:
- en
library_name: transformers
pipeline_tag: zero-shot-classification
base_model: answerdotai/ModernBERT-base
tags:
- decision-model
- calibration
- multi-label
- jev
- jev-alternative
- system-one
datasets:
- Anthropic/hh-rlhf
- Deysi/spam-detection-dataset
- GBaker/MedQA-USMLE-4-options
- HuggingFaceH4/ultrafeedback_binarized
- Intel/orca_dpo_pairs
- SetFit/amazon_massive_intent_en-US
- SetFit/amazon_massive_scenario_en-US
- SetFit/student-question-categories
- TIGER-Lab/MMLU-Pro
- TimSchopf/medical_abstracts
- allenai/ai2_arc
- allenai/openbookqa
- allenai/prosocial-dialog
- allenai/quartz
- allenai/reward-bench
- allenai/scitail
- allenai/winogrande
- aps/super_glue
- benayas/snips
- bitext/Bitext-customer-support-llm-chatbot-training-dataset
- cais/mmlu
- chengxuphd/liar2
- clinc/clinc_oos
- coastalcph/lex_glue
- deepset/prompt-injections
- demelin/moral_stories
- fancyzhx/dbpedia_14
- gfissore/arxiv-abstracts-2021
- glaiveai/glaive-function-calling-v2
- gonglinyuan/CoSQA
- google-research-datasets/go_emotions
- google-research-datasets/paws
- google-research-datasets/poem_sentiment
- google/boolq
- google/civil_comments
- gretelai/symptom_to_diagnosis
- hendrycks/ethics
- jackhhao/jailbreak-classification
- jakartaresearch/semeval-absa
- lmsys/mt_bench_human_judgments
- marksverdhei/clickbait_title_classification
- mikex86/stackoverflow-posts
- mmathys/openai-moderation-api-evaluation
- mteb/amazon_counterfactual
- mteb/banking77
- mteb/toxic_conversations_50k
- nvidia/Aegis-AI-Content-Safety-Dataset-2.0
- nvidia/HelpSteer
- nvidia/HelpSteer2
- nyu-mll/glue
- nyu-mll/multi_nli
- openlifescienceai/medmcqa
- owaiskha9654/PubMed_MultiLabel_Text_Classification_Dataset_MeSH
- pminervini/HaluEval
- prometheus-eval/Feedback-Collection
- prometheus-eval/Preference-Collection
- qiaojin/PubMedQA
- rajpurkar/squad_v2
- reshabhs/SPML_Chatbot_Prompt_Injection
- stanfordnlp/snli
- tals/vitaminc
- tasksource/bigbench
- tasksource/crowdflower
- tasksource/esci
- tasksource/folio
- tau/commonsense_qa
- tdavidson/hate_speech_offensive
- thesofakillers/jigsaw-toxic-comment-classification-challenge
- truthfulqa/truthful_qa
- ucirvine/sms_spam
- zeroshot/twitter-financial-news-sentiment
- zeroshot/twitter-financial-news-topic
---
#  WaterSheep
[Website](https://samratduttaofficial.github.io/WaterSheep/) · [Demo](https://huggingface.co/spaces/samratduttaofficial/WaterSheep) · [Code](https://github.com/SamratDuttaOfficial/WaterSheep) · [Video](https://youtu.be/VjSiBecOiRI)
WaterSheep answers yes/no, single-choice, rating and multi-label questions about any text, with a
probability for every option. Version 0.1.0 (`watersheep-20260928-125452`).
## Usage
```bash
pip install transformers torch
```
```python
from transformers import pipeline
ws = pipeline(model="samratduttaofficial/WaterSheep", trust_remote_code=True)
ws("I was charged twice.", question="Which team should handle this?", options=["billing", "shipping", "support"])
```
| Type | Options | Answer |
|---|---|---|
| `noul` | none (yes/no) | probability of yes |
| `choice` | any labels | the best option |
| `score` | a digit scale, e.g. `1` to `5` | the expected level |
| `multi` | any labels, with `type="multi"` | every option above the threshold |
Every answer includes a probability for each option.
## Using Jev?
WaterSheep is an open-source alternative to Jev. Run it as a local server:
```bash
pip install git+https://github.com/SamratDuttaOfficial/WaterSheep
watersheep --model samratduttaofficial/WaterSheep --serve
```
It answers Jev's `POST /v1/systemone` requests on your machine, and TypeSafe's Python SDK works against it
without code changes:
```bash
export TYPESAFE_BASE_URL=http://127.0.0.1:8766
```
Any API key value works locally. Multi-label questions (`"type": "multi"`) work too, as plain JSON.
WaterSheep is independent and not affiliated with TypeSafe AI.
## Download
```bash
hf download samratduttaofficial/WaterSheep --local-dir WaterSheep
```
Or with Git (requires Git LFS):
```bash
git clone https://huggingface.co/samratduttaofficial/WaterSheep
```
Then load it from the folder, offline:
```python
ws = pipeline(model="WaterSheep", trust_remote_code=True)
```
## API
Deploy it as an [Inference Endpoint](https://endpoints.huggingface.co), then:
```bash
curl https://YOUR-ENDPOINT -H "Authorization: Bearer $HF_TOKEN" -H "Content-Type: application/json" -d '{"inputs": "I was charged twice.", "parameters": {"question": "Which team should handle this?", "options": ["billing", "shipping", "support"]}}'
```
## JavaScript
No install; runs in the browser:
```html
<script type="module">
import { decide } from "https://samratduttaofficial.github.io/WaterSheep/watersheep.js";
console.log(await decide("I was charged twice.", "Which team should handle this?", ["billing", "shipping", "support"]));
</script>
```
With a downloaded copy on your web server, call `load({ base: "WaterSheep/" })` first.
Other languages: run `onnx/model_quantized.onnx` with ONNX Runtime; `watersheep.js` shows the input format.
## Evaluation
| Evaluation | Accuracy | ECE |
|---|---|---|
| In-distribution test split | 77.8% | 0.026 |
| Held-out datasets, not seen in training | 61.2% | 0.043 |
ECE is the expected calibration error (lower is better).
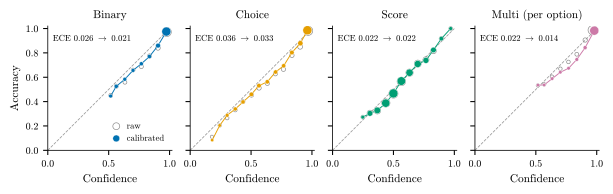
Accuracy against confidence for each question type, before (raw) and after calibration.
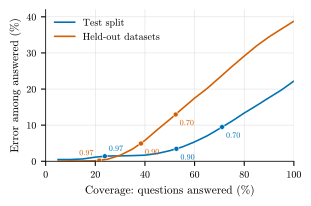
Error among the questions answered when the model only answers above a confidence threshold. The dots mark thresholds of 0.70, 0.90 and 0.97.
### Benchmarks
| Benchmark | Suite | Questions | Accuracy | ECE | In training data |
|---|---|---|---|---|---|
| [goemotions](https://huggingface.co/datasets/google-research-datasets/go_emotions) | sentiment | 2000 | 22.4% | 0.023 | other split |
| [hatecheck](https://huggingface.co/datasets/Paul/hatecheck) | safety | 2000 | 75.1% | 0.139 | no |
| [legal_abercrombie](https://huggingface.co/datasets/nguha/legalbench) | legal | 95 | 21.1% | 0.316 | no |
| [legal_contract_nli_confidentiality_of_agreement](https://huggingface.co/datasets/nguha/legalbench) | legal | 82 | 69.5% | 0.177 | no |
| [legal_corporate_lobbying](https://huggingface.co/datasets/nguha/legalbench) | legal | 490 | 68.4% | 0.216 | no |
| [legal_cuad_audit_rights](https://huggingface.co/datasets/nguha/legalbench) | legal | 1216 | 86.3% | 0.041 | no |
| [legal_definition_classification](https://huggingface.co/datasets/nguha/legalbench) | legal | 1337 | 56.9% | 0.279 | no |
| [legal_function_of_decision_section](https://huggingface.co/datasets/nguha/legalbench) | legal | 367 | 24.3% | 0.245 | no |
| [legal_hearsay](https://huggingface.co/datasets/nguha/legalbench) | legal | 94 | 56.4% | 0.307 | no |
| [legal_overruling](https://huggingface.co/datasets/nguha/legalbench) | legal | 2000 | 62.5% | 0.151 | no |
| [legal_personal_jurisdiction](https://huggingface.co/datasets/nguha/legalbench) | legal | 50 | 50.0% | 0.160 | no |
| [legal_privacy_policy_qa](https://huggingface.co/datasets/nguha/legalbench) | legal | 2000 | 58.9% | 0.274 | no |
| [legal_proa](https://huggingface.co/datasets/nguha/legalbench) | legal | 95 | 51.6% | 0.379 | no |
| [legal_ucc_v_common_law](https://huggingface.co/datasets/nguha/legalbench) | legal | 94 | 62.8% | 0.171 | no |
| [prompt_injection](https://huggingface.co/datasets/deepset/prompt-injections) | safety | 116 | 91.4% | 0.079 | other split |
| [xstest](https://huggingface.co/datasets/Paul/XSTest) | safety | 450 | 73.6% | 0.140 | no |
## Training
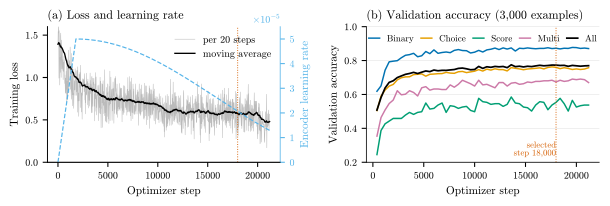
Training loss and learning rate (left); validation accuracy by question type (right).
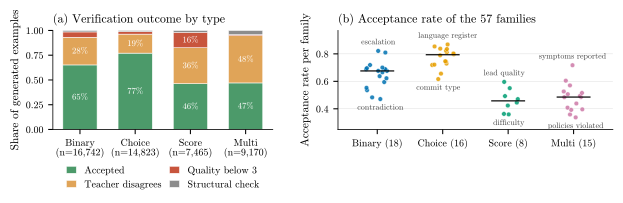
Share of synthetic examples kept after verification, by question type (left) and by family (right).
## Limitations
- English only.
- Long inputs are truncated. The `watersheep` package and its server mark such answers with `"truncated": true`.
- Rating-scale answers are less accurate than the other types.
- Probabilities are calibrated on data like the training data; validate them on your own.
- Not for high-stakes decisions (medical, legal, financial, hiring) on its own.
## License
Apache 2.0 (`LICENSE`). Trained on openly licensed data; credits in `NOTICE`.
## Citation
```bibtex
@misc{watersheep,
author = {Samrat Dutta},
title = {WaterSheep: calibrated decisions for any text},
year = {2026},
url = {https://huggingface.co/samratduttaofficial/WaterSheep}
}
```
---
<p align="center">
<a href="https://doi.org/10.13140/RG.2.2.28606.45122"><img src="https://samratduttaofficial.github.io/WaterSheep/preprint.svg" alt="Read the preprint" width="400"></a>
<a href="https://buymeacoffee.com/samratdutta"><img src="https://samratduttaofficial.github.io/WaterSheep/coffee.svg" alt="Buy me a coffee" width="400"></a>
</p>
|