


R1: streaming end-of-turn heads on the Smart Turn v3.2 encoder
Browse files- AMI_LICENCE.txt +307 -0
- ATTRIBUTION.md +47 -0
- LICENSE +25 -0
- README.md +225 -0
- SHA256SUMS +12 -0
- eot-heads-v32.onnx +3 -0
- eval/ami_dev.csv +0 -0
- eval/ami_eval.py +451 -0
- eval/ami_eval_reference.md +48 -0
- eval/ami_test.csv +0 -0
- rules/eager_tables.csv +9 -0
- rules/theta_tables.csv +7 -0
- smart-turn-v3.2-encoder-pooled.onnx +3 -0
AMI_LICENCE.txt
ADDED
|
@@ -0,0 +1,307 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
The AMI corpus and its annotations are released under the Creative
|
| 2 |
+
Commons Attribution 4.0 International Public License agreement (CC BY
|
| 3 |
+
4.0). Use of this data implies agreement with the terms below. See
|
| 4 |
+
also: https://creativecommons.org/licenses/by/4.0/
|
| 5 |
+
|
| 6 |
+
|
| 7 |
+
THE WORK (AS DEFINED BELOW) IS PROVIDED UNDER THE TERMS OF THIS
|
| 8 |
+
CREATIVE COMMONS PUBLIC LICENSE ("CCPL" OR "LICENSE"). THE WORK IS
|
| 9 |
+
PROTECTED BY COPYRIGHT AND/OR OTHER APPLICABLE LAW. ANY USE OF THE
|
| 10 |
+
WORK OTHER THAN AS AUTHORIZED UNDER THIS LICENSE OR COPYRIGHT LAW IS
|
| 11 |
+
PROHIBITED.
|
| 12 |
+
|
| 13 |
+
BY EXERCISING ANY RIGHTS TO THE WORK PROVIDED HERE, YOU ACCEPT AND
|
| 14 |
+
AGREE TO BE BOUND BY THE TERMS OF THIS LICENSE. THE LICENSOR GRANTS
|
| 15 |
+
YOU THE RIGHTS CONTAINED HERE IN CONSIDERATION OF YOUR ACCEPTANCE OF
|
| 16 |
+
SUCH TERMS AND CONDITIONS.
|
| 17 |
+
|
| 18 |
+
Section 1 – Definitions.
|
| 19 |
+
|
| 20 |
+
a. Adapted Material means material subject to Copyright and Similar
|
| 21 |
+
Rights that is derived from or based upon the Licensed Material and in
|
| 22 |
+
which the Licensed Material is translated, altered, arranged,
|
| 23 |
+
transformed, or otherwise modified in a manner requiring permission
|
| 24 |
+
under the Copyright and Similar Rights held by the Licensor. For
|
| 25 |
+
purposes of this Public License, where the Licensed Material is a
|
| 26 |
+
musical work, performance, or sound recording, Adapted Material is
|
| 27 |
+
always produced where the Licensed Material is synched in timed
|
| 28 |
+
relation with a moving image.
|
| 29 |
+
|
| 30 |
+
b. Adapter's License means the license You apply to Your Copyright and
|
| 31 |
+
Similar Rights in Your contributions to Adapted Material in accordance
|
| 32 |
+
with the terms and conditions of this Public License.
|
| 33 |
+
|
| 34 |
+
c. Copyright and Similar Rights means copyright and/or similar rights
|
| 35 |
+
closely related to copyright including, without limitation,
|
| 36 |
+
performance, broadcast, sound recording, and Sui Generis Database
|
| 37 |
+
Rights, without regard to how the rights are labeled or
|
| 38 |
+
categorized. For purposes of this Public License, the rights specified
|
| 39 |
+
in Section 2(b)(1)-(2) are not Copyright and Similar Rights.
|
| 40 |
+
|
| 41 |
+
d. Effective Technological Measures means those measures that, in the
|
| 42 |
+
absence of proper authority, may not be circumvented under laws
|
| 43 |
+
fulfilling obligations under Article 11 of the WIPO Copyright Treaty
|
| 44 |
+
adopted on December 20, 1996, and/or similar international agreements.
|
| 45 |
+
|
| 46 |
+
e. Exceptions and Limitations means fair use, fair dealing, and/or any
|
| 47 |
+
other exception or limitation to Copyright and Similar Rights that
|
| 48 |
+
applies to Your use of the Licensed Material.
|
| 49 |
+
|
| 50 |
+
f. Licensed Material means the artistic or literary work, database, or
|
| 51 |
+
other material to which the Licensor applied this Public License.
|
| 52 |
+
|
| 53 |
+
g. Licensed Rights means the rights granted to You subject to the
|
| 54 |
+
terms and conditions of this Public License, which are limited to all
|
| 55 |
+
Copyright and Similar Rights that apply to Your use of the Licensed
|
| 56 |
+
Material and that the Licensor has authority to license.
|
| 57 |
+
|
| 58 |
+
h. Licensor means the individual(s) or entity(ies) granting rights
|
| 59 |
+
under this Public License.
|
| 60 |
+
|
| 61 |
+
i. Share means to provide material to the public by any means or
|
| 62 |
+
process that requires permission under the Licensed Rights, such as
|
| 63 |
+
reproduction, public display, public performance, distribution,
|
| 64 |
+
dissemination, communication, or importation, and to make material
|
| 65 |
+
available to the public including in ways that members of the public
|
| 66 |
+
may access the material from a place and at a time individually chosen
|
| 67 |
+
by them.
|
| 68 |
+
|
| 69 |
+
j. Sui Generis Database Rights means rights other than copyright
|
| 70 |
+
resulting from Directive 96/9/EC of the European Parliament and of the
|
| 71 |
+
Council of 11 March 1996 on the legal protection of databases, as
|
| 72 |
+
amended and/or succeeded, as well as other essentially equivalent
|
| 73 |
+
rights anywhere in the world.
|
| 74 |
+
|
| 75 |
+
k. You means the individual or entity exercising the Licensed Rights
|
| 76 |
+
under this Public License. Your has a corresponding meaning.
|
| 77 |
+
|
| 78 |
+
|
| 79 |
+
Section 2 – Scope.
|
| 80 |
+
|
| 81 |
+
a. License grant.
|
| 82 |
+
|
| 83 |
+
1. Subject to the terms and conditions of this Public License, the
|
| 84 |
+
Licensor hereby grants You a worldwide, royalty-free,
|
| 85 |
+
non-sublicensable, non-exclusive, irrevocable license to exercise the
|
| 86 |
+
Licensed Rights in the Licensed Material to:
|
| 87 |
+
A. reproduce and Share the Licensed Material, in whole or in part; and
|
| 88 |
+
B. produce, reproduce, and Share Adapted Material.
|
| 89 |
+
|
| 90 |
+
2. Exceptions and Limitations. For the avoidance of doubt, where
|
| 91 |
+
Exceptions and Limitations apply to Your use, this Public License does
|
| 92 |
+
not apply, and You do not need to comply with its terms and
|
| 93 |
+
conditions.
|
| 94 |
+
|
| 95 |
+
3. Term. The term of this Public License is specified in Section 6(a).
|
| 96 |
+
|
| 97 |
+
4. Media and formats; technical modifications allowed. The Licensor
|
| 98 |
+
authorizes You to exercise the Licensed Rights in all media and
|
| 99 |
+
formats whether now known or hereafter created, and to make technical
|
| 100 |
+
modifications necessary to do so. The Licensor waives and/or agrees
|
| 101 |
+
not to assert any right or authority to forbid You from making
|
| 102 |
+
technical modifications necessary to exercise the Licensed Rights,
|
| 103 |
+
including technical modifications necessary to circumvent Effective
|
| 104 |
+
Technological Measures. For purposes of this Public License, simply
|
| 105 |
+
making modifications authorized by this Section 2(a)(4) never produces
|
| 106 |
+
Adapted Material.
|
| 107 |
+
|
| 108 |
+
5. Downstream recipients.
|
| 109 |
+
|
| 110 |
+
A. Offer from the Licensor – Licensed Material. Every recipient of
|
| 111 |
+
the Licensed Material automatically receives an offer from the
|
| 112 |
+
Licensor to exercise the Licensed Rights under the terms and
|
| 113 |
+
conditions of this Public License.
|
| 114 |
+
|
| 115 |
+
B. No downstream restrictions. You may not offer or impose any
|
| 116 |
+
additional or different terms or conditions on, or apply any
|
| 117 |
+
Effective Technological Measures to, the Licensed Material if doing
|
| 118 |
+
so restricts exercise of the Licensed Rights by any recipient of the
|
| 119 |
+
Licensed Material.
|
| 120 |
+
|
| 121 |
+
6. No endorsement. Nothing in this Public License constitutes or may
|
| 122 |
+
be construed as permission to assert or imply that You are, or that
|
| 123 |
+
Your use of the Licensed Material is, connected with, or sponsored,
|
| 124 |
+
endorsed, or granted official status by, the Licensor or others
|
| 125 |
+
designated to receive attribution as provided in Section
|
| 126 |
+
3(a)(1)(A)(i).
|
| 127 |
+
|
| 128 |
+
b. Other rights.
|
| 129 |
+
|
| 130 |
+
1. Moral rights, such as the right of integrity, are not licensed
|
| 131 |
+
under this Public License, nor are publicity, privacy, and/or other
|
| 132 |
+
similar personality rights; however, to the extent possible, the
|
| 133 |
+
Licensor waives and/or agrees not to assert any such rights held by
|
| 134 |
+
the Licensor to the limited extent necessary to allow You to exercise
|
| 135 |
+
the Licensed Rights, but not otherwise.
|
| 136 |
+
|
| 137 |
+
2. Patent and trademark rights are not licensed under this Public License.
|
| 138 |
+
|
| 139 |
+
3. To the extent possible, the Licensor waives any right to collect
|
| 140 |
+
royalties from You for the exercise of the Licensed Rights, whether
|
| 141 |
+
directly or through a collecting society under any voluntary or
|
| 142 |
+
waivable statutory or compulsory licensing scheme. In all other cases
|
| 143 |
+
the Licensor expressly reserves any right to collect such royalties.
|
| 144 |
+
|
| 145 |
+
|
| 146 |
+
Section 3 – License Conditions.
|
| 147 |
+
|
| 148 |
+
Your exercise of the Licensed Rights is expressly made subject to the
|
| 149 |
+
following conditions.
|
| 150 |
+
|
| 151 |
+
a. Attribution.
|
| 152 |
+
|
| 153 |
+
1. If You Share the Licensed Material (including in modified form),
|
| 154 |
+
You must:
|
| 155 |
+
|
| 156 |
+
A. retain the following if it is supplied by the Licensor with the
|
| 157 |
+
Licensed Material:
|
| 158 |
+
|
| 159 |
+
i. identification of the creator(s) of the Licensed Material and
|
| 160 |
+
any others designated to receive attribution, in any reasonable
|
| 161 |
+
manner requested by the Licensor (including by pseudonym if
|
| 162 |
+
designated);
|
| 163 |
+
|
| 164 |
+
ii. a copyright notice;
|
| 165 |
+
|
| 166 |
+
iii. a notice that refers to this Public License;
|
| 167 |
+
|
| 168 |
+
iv. a notice that refers to the disclaimer of warranties;
|
| 169 |
+
|
| 170 |
+
v. a URI or hyperlink to the Licensed Material to the extent
|
| 171 |
+
reasonably practicable;
|
| 172 |
+
|
| 173 |
+
B. indicate if You modified the Licensed Material and retain an
|
| 174 |
+
indication of any previous modifications; and
|
| 175 |
+
|
| 176 |
+
C. indicate the Licensed Material is licensed under this Public
|
| 177 |
+
License, and include the text of, or the URI or hyperlink to, this
|
| 178 |
+
Public License.
|
| 179 |
+
|
| 180 |
+
2. You may satisfy the conditions in Section 3(a)(1) in any reasonable
|
| 181 |
+
manner based on the medium, means, and context in which You Share the
|
| 182 |
+
Licensed Material. For example, it may be reasonable to satisfy the
|
| 183 |
+
conditions by providing a URI or hyperlink to a resource that includes
|
| 184 |
+
the required information.
|
| 185 |
+
|
| 186 |
+
3. If requested by the Licensor, You must remove any of the
|
| 187 |
+
information required by Section 3(a)(1)(A) to the extent reasonably
|
| 188 |
+
practicable.
|
| 189 |
+
|
| 190 |
+
4. If You Share Adapted Material You produce, the Adapter's License
|
| 191 |
+
You apply must not prevent recipients of the Adapted Material from
|
| 192 |
+
complying with this Public License.
|
| 193 |
+
|
| 194 |
+
|
| 195 |
+
Section 4 – Sui Generis Database Rights.
|
| 196 |
+
|
| 197 |
+
Where the Licensed Rights include Sui Generis Database Rights that
|
| 198 |
+
apply to Your use of the Licensed Material:
|
| 199 |
+
|
| 200 |
+
a. for the avoidance of doubt, Section 2(a)(1) grants You the right to
|
| 201 |
+
extract, reuse, reproduce, and Share all or a substantial portion of
|
| 202 |
+
the contents of the database;
|
| 203 |
+
|
| 204 |
+
b. if You include all or a substantial portion of the database
|
| 205 |
+
contents in a database in which You have Sui Generis Database Rights,
|
| 206 |
+
then the database in which You have Sui Generis Database Rights (but
|
| 207 |
+
not its individual contents) is Adapted Material; and
|
| 208 |
+
|
| 209 |
+
c. You must comply with the conditions in Section 3(a) if You Share
|
| 210 |
+
all or a substantial portion of the contents of the database.
|
| 211 |
+
|
| 212 |
+
For the avoidance of doubt, this Section 4 supplements and does not
|
| 213 |
+
replace Your obligations under this Public License where the Licensed
|
| 214 |
+
Rights include other Copyright and Similar Rights.
|
| 215 |
+
|
| 216 |
+
|
| 217 |
+
Section 5 – Disclaimer of Warranties and Limitation of Liability.
|
| 218 |
+
|
| 219 |
+
a. Unless otherwise separately undertaken by the Licensor, to the
|
| 220 |
+
extent possible, the Licensor offers the Licensed Material as-is and
|
| 221 |
+
as-available, and makes no representations or warranties of any kind
|
| 222 |
+
concerning the Licensed Material, whether express, implied, statutory,
|
| 223 |
+
or other. This includes, without limitation, warranties of title,
|
| 224 |
+
merchantability, fitness for a particular purpose, non-infringement,
|
| 225 |
+
absence of latent or other defects, accuracy, or the presence or
|
| 226 |
+
absence of errors, whether or not known or discoverable. Where
|
| 227 |
+
disclaimers of warranties are not allowed in full or in part, this
|
| 228 |
+
disclaimer may not apply to You.
|
| 229 |
+
|
| 230 |
+
b. To the extent possible, in no event will the Licensor be liable to
|
| 231 |
+
You on any legal theory (including, without limitation, negligence) or
|
| 232 |
+
otherwise for any direct, special, indirect, incidental,
|
| 233 |
+
consequential, punitive, exemplary, or other losses, costs, expenses,
|
| 234 |
+
or damages arising out of this Public License or use of the Licensed
|
| 235 |
+
Material, even if the Licensor has been advised of the possibility of
|
| 236 |
+
such losses, costs, expenses, or damages. Where a limitation of
|
| 237 |
+
liability is not allowed in full or in part, this limitation may not
|
| 238 |
+
apply to You.
|
| 239 |
+
|
| 240 |
+
c. The disclaimer of warranties and limitation of liability provided
|
| 241 |
+
above shall be interpreted in a manner that, to the extent possible,
|
| 242 |
+
most closely approximates an absolute disclaimer and waiver of all
|
| 243 |
+
liability.
|
| 244 |
+
|
| 245 |
+
|
| 246 |
+
Section 6 – Term and Termination.
|
| 247 |
+
|
| 248 |
+
a. This Public License applies for the term of the Copyright and
|
| 249 |
+
Similar Rights licensed here. However, if You fail to comply with this
|
| 250 |
+
Public License, then Your rights under this Public License terminate
|
| 251 |
+
automatically.
|
| 252 |
+
|
| 253 |
+
b. Where Your right to use the Licensed Material has terminated under
|
| 254 |
+
Section 6(a), it reinstates:
|
| 255 |
+
|
| 256 |
+
1. automatically as of the date the violation is cured, provided it
|
| 257 |
+
is cured within 30 days of Your discovery of the violation; or
|
| 258 |
+
|
| 259 |
+
2. upon express reinstatement by the Licensor.
|
| 260 |
+
|
| 261 |
+
For the avoidance of doubt, this Section 6(b) does not affect any
|
| 262 |
+
right the Licensor may have to seek remedies for Your violations of
|
| 263 |
+
this Public License.
|
| 264 |
+
|
| 265 |
+
|
| 266 |
+
c. For the avoidance of doubt, the Licensor may also offer the
|
| 267 |
+
Licensed Material under separate terms or conditions or stop
|
| 268 |
+
distributing the Licensed Material at any time; however, doing so will
|
| 269 |
+
not terminate this Public License.
|
| 270 |
+
|
| 271 |
+
d. Sections 1, 5, 6, 7, and 8 survive termination of this Public
|
| 272 |
+
License.
|
| 273 |
+
|
| 274 |
+
|
| 275 |
+
Section 7 – Other Terms and Conditions.
|
| 276 |
+
|
| 277 |
+
a. The Licensor shall not be bound by any additional or different
|
| 278 |
+
terms or conditions communicated by You unless expressly agreed.
|
| 279 |
+
|
| 280 |
+
b. Any arrangements, understandings, or agreements regarding the
|
| 281 |
+
Licensed Material not stated herein are separate from and independent
|
| 282 |
+
of the terms and conditions of this Public License.
|
| 283 |
+
|
| 284 |
+
|
| 285 |
+
Section 8 – Interpretation.
|
| 286 |
+
|
| 287 |
+
a. For the avoidance of doubt, this Public License does not, and shall
|
| 288 |
+
not be interpreted to, reduce, limit, restrict, or impose conditions
|
| 289 |
+
on any use of the Licensed Material that could lawfully be made
|
| 290 |
+
without permission under this Public License.
|
| 291 |
+
|
| 292 |
+
b. To the extent possible, if any provision of this Public License is
|
| 293 |
+
deemed unenforceable, it shall be automatically reformed to the
|
| 294 |
+
minimum extent necessary to make it enforceable. If the provision
|
| 295 |
+
cannot be reformed, it shall be severed from this Public License
|
| 296 |
+
without affecting the enforceability of the remaining terms and
|
| 297 |
+
conditions.
|
| 298 |
+
|
| 299 |
+
c. No term or condition of this Public License will be waived and no
|
| 300 |
+
failure to comply consented to unless expressly agreed to by the
|
| 301 |
+
Licensor.
|
| 302 |
+
|
| 303 |
+
d. Nothing in this Public License constitutes or may be interpreted as
|
| 304 |
+
a limitation upon, or waiver of, any privileges and immunities that
|
| 305 |
+
apply to the Licensor or You, including from the legal processes of
|
| 306 |
+
any jurisdiction or authority.
|
| 307 |
+
|
ATTRIBUTION.md
ADDED
|
@@ -0,0 +1,47 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Attribution and licences
|
| 2 |
+
|
| 3 |
+
## This release
|
| 4 |
+
|
| 5 |
+
The trained heads (`eot-heads-v32.onnx`), the decision-rule tables (`rules/`), the evaluation
|
| 6 |
+
script and manifests (`eval/`) and the model card are released by susuROBO under the BSD 2-Clause
|
| 7 |
+
License (`LICENSE`).
|
| 8 |
+
|
| 9 |
+
## Encoder: Smart Turn v3.2 (Daily / Pipecat)
|
| 10 |
+
|
| 11 |
+
`smart-turn-v3.2-encoder-pooled.onnx` is Pipecat's `smart-turn-v3.2-gpu.onnx`
|
| 12 |
+
(https://huggingface.co/pipecat-ai/smart-turn-v3, BSD 2-Clause, Copyright (c) 2024–2025 Daily)
|
| 13 |
+
with one change: the attention-pooled 384-d vector that feeds the model's own classifier is added
|
| 14 |
+
as a second graph output (`sum_1`). Weights are unchanged, so the first output (`logits`) is
|
| 15 |
+
bit-exact with the original model. The encoder architecture is OpenAI's Whisper-tiny encoder
|
| 16 |
+
(MIT), as fine-tuned by Pipecat on `pipecat-ai/smart-turn-data-v3.2-train`.
|
| 17 |
+
|
| 18 |
+
## Training data of the heads
|
| 19 |
+
|
| 20 |
+
- `pipecat-ai/smart-turn-data-v3.2-train` (Pipecat; the τ-padded and pre-offset variants described
|
| 21 |
+
in the model card are derived from it on the fly and are not redistributed).
|
| 22 |
+
- **AMI Meeting Corpus** (University of Edinburgh and the AMI consortium),
|
| 23 |
+
https://groups.inf.ed.ac.uk/ami/corpus/, released under the Creative Commons Attribution 4.0
|
| 24 |
+
International licence (`AMI_LICENCE.txt`, the licence text shipped with the corpus annotations,
|
| 25 |
+
release 1.7). The per-speaker close-talking headset recordings and the NXT word alignments were
|
| 26 |
+
used; the heads were trained on the 137 Kaldi-recipe training meetings.
|
| 27 |
+
|
| 28 |
+
Citation: J. Carletta et al., "The AMI Meeting Corpus: A Pre-announcement", in *Machine Learning
|
| 29 |
+
for Multimodal Interaction (MLMI 2005)*, LNCS 3869, Springer, 2006, pp. 28–39.
|
| 30 |
+
|
| 31 |
+
## Evaluation manifests (`eval/ami_dev.csv`, `eval/ami_test.csv`)
|
| 32 |
+
|
| 33 |
+
Derived from the AMI Meeting Corpus (CC BY 4.0) and redistributed under the same licence with
|
| 34 |
+
attribution to the corpus authors above. Each row is one labelled silence of one speaker:
|
| 35 |
+
`meeting`, `speaker` (NXT agent letter), `channel` (headset number in the corpus audio), `t` (the
|
| 36 |
+
speaker's VAD stop, seconds into the meeting), `label` (`complete`: another participant took the
|
| 37 |
+
floor within 3 s; `incomplete`: the speaker resumed), `gap_s` (incomplete: length of the pause),
|
| 38 |
+
`b_onset_s` (complete: the next speaker's onset after `t`), `a_turn_s` (speech in the speaker's turn
|
| 39 |
+
so far). The VAD comes from Silero run on the headset audio and gated by the transcript; the
|
| 40 |
+
labelling rules are documented in the public repository (`docs/a2_ami.md`). The dev split is the
|
| 41 |
+
Kaldi AMI recipe's dev set (18 meetings), the test split its eval set (16 meetings). Audio is not
|
| 42 |
+
redistributed: `eval/ami_eval.py` downloads the headset files it needs from the corpus mirror.
|
| 43 |
+
|
| 44 |
+
## Not used
|
| 45 |
+
|
| 46 |
+
Nothing in this release was trained or fitted on Meta's Seamless Interaction dataset (CC BY-NC) or
|
| 47 |
+
on Meta's Casual Conversations dataset.
|
LICENSE
ADDED
|
@@ -0,0 +1,25 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
BSD 2-Clause License
|
| 2 |
+
|
| 3 |
+
Copyright (c) 2026, susuROBO
|
| 4 |
+
Copyright (c) 2024–2025, Daily
|
| 5 |
+
|
| 6 |
+
Redistribution and use in source and binary forms, with or without
|
| 7 |
+
modification, are permitted provided that the following conditions are met:
|
| 8 |
+
|
| 9 |
+
1. Redistributions of source code must retain the above copyright notice, this
|
| 10 |
+
list of conditions and the following disclaimer.
|
| 11 |
+
|
| 12 |
+
2. Redistributions in binary form must reproduce the above copyright notice,
|
| 13 |
+
this list of conditions and the following disclaimer in the documentation
|
| 14 |
+
and/or other materials provided with the distribution.
|
| 15 |
+
|
| 16 |
+
THIS SOFTWARE IS PROVIDED BY THE COPYRIGHT HOLDERS AND CONTRIBUTORS "AS IS"
|
| 17 |
+
AND ANY EXPRESS OR IMPLIED WARRANTIES, INCLUDING, BUT NOT LIMITED TO, THE
|
| 18 |
+
IMPLIED WARRANTIES OF MERCHANTABILITY AND FITNESS FOR A PARTICULAR PURPOSE ARE
|
| 19 |
+
DISCLAIMED. IN NO EVENT SHALL THE COPYRIGHT HOLDER OR CONTRIBUTORS BE LIABLE
|
| 20 |
+
FOR ANY DIRECT, INDIRECT, INCIDENTAL, SPECIAL, EXEMPLARY, OR CONSEQUENTIAL
|
| 21 |
+
DAMAGES (INCLUDING, BUT NOT LIMITED TO, PROCUREMENT OF SUBSTITUTE GOODS OR
|
| 22 |
+
SERVICES; LOSS OF USE, DATA, OR PROFITS; OR BUSINESS INTERRUPTION) HOWEVER
|
| 23 |
+
CAUSED AND ON ANY THEORY OF LIABILITY, WHETHER IN CONTRACT, STRICT LIABILITY,
|
| 24 |
+
OR TORT (INCLUDING NEGLIGENCE OR OTHERWISE) ARISING IN ANY WAY OUT OF THE USE
|
| 25 |
+
OF THIS SOFTWARE, EVEN IF ADVISED OF THE POSSIBILITY OF SUCH DAMAGE.
|
README.md
ADDED
|
@@ -0,0 +1,225 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
---
|
| 2 |
+
license: bsd-2-clause
|
| 3 |
+
library_name: onnx
|
| 4 |
+
pipeline_tag: audio-classification
|
| 5 |
+
tags:
|
| 6 |
+
- turn-detection
|
| 7 |
+
- end-of-turn
|
| 8 |
+
- voice-agents
|
| 9 |
+
- pipecat
|
| 10 |
+
- streaming
|
| 11 |
+
- onnx
|
| 12 |
+
datasets:
|
| 13 |
+
- pipecat-ai/smart-turn-data-v3.2-train
|
| 14 |
+
language:
|
| 15 |
+
- en
|
| 16 |
+
- multilingual
|
| 17 |
+
base_model: pipecat-ai/smart-turn-v3
|
| 18 |
+
---
|
| 19 |
+
|
| 20 |
+
# Smart Turn streaming end-of-turn heads (R1, audio-only)
|
| 21 |
+
|
| 22 |
+
A silence-aware, streaming end-of-turn detector for voice agents, built on Pipecat's frozen
|
| 23 |
+
[Smart Turn v3.2](https://huggingface.co/pipecat-ai/smart-turn-v3) encoder. Instead of one query
|
| 24 |
+
at the VAD stop followed by a 3 s timeout, it scores the conversation every 100 ms on the CPU and
|
| 25 |
+
decides at 0.2 / 0.5 / 1.2 s of silence with thresholds fitted to a false-alarm budget. On real
|
| 26 |
+
multi-party conversation (AMI Meeting Corpus) it ends the turn on 5 % of mid-turn pauses where the
|
| 27 |
+
stock rule fires on 42 %, and brings the 90th-percentile response time from 3.2 s to 1.3 s. It runs
|
| 28 |
+
at about 9 % of one Apple M4 core single-threaded, with numpy and onnxruntime only.
|
| 29 |
+
|
| 30 |
+
Code (Pipecat 1.14 turn analyzer, eager-then-commit stop strategy, training and evaluation):
|
| 31 |
+
[github.com/OpenHRIai/smart-turn-streaming](https://github.com/OpenHRIai/smart-turn-streaming).
|
| 32 |
+
|
| 33 |
+
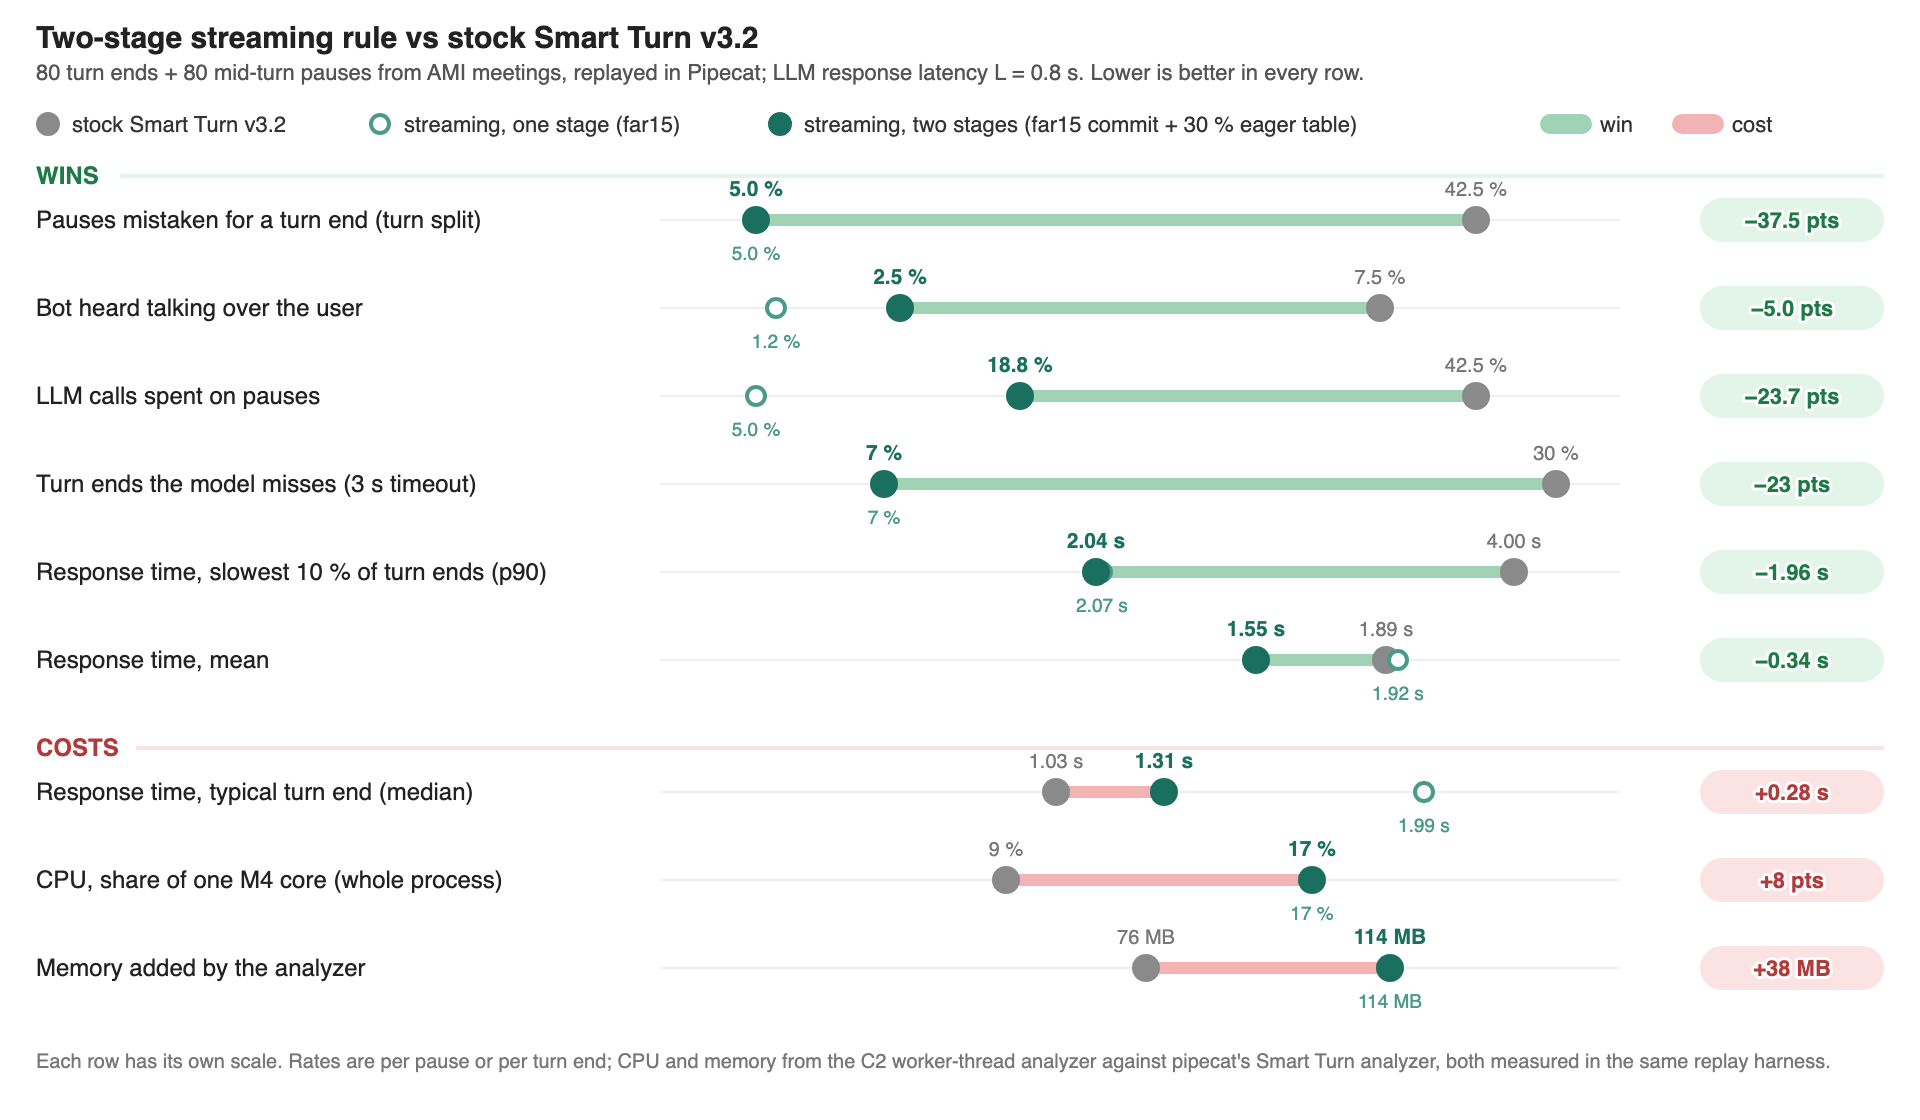
|
| 34 |
+
|
| 35 |
+
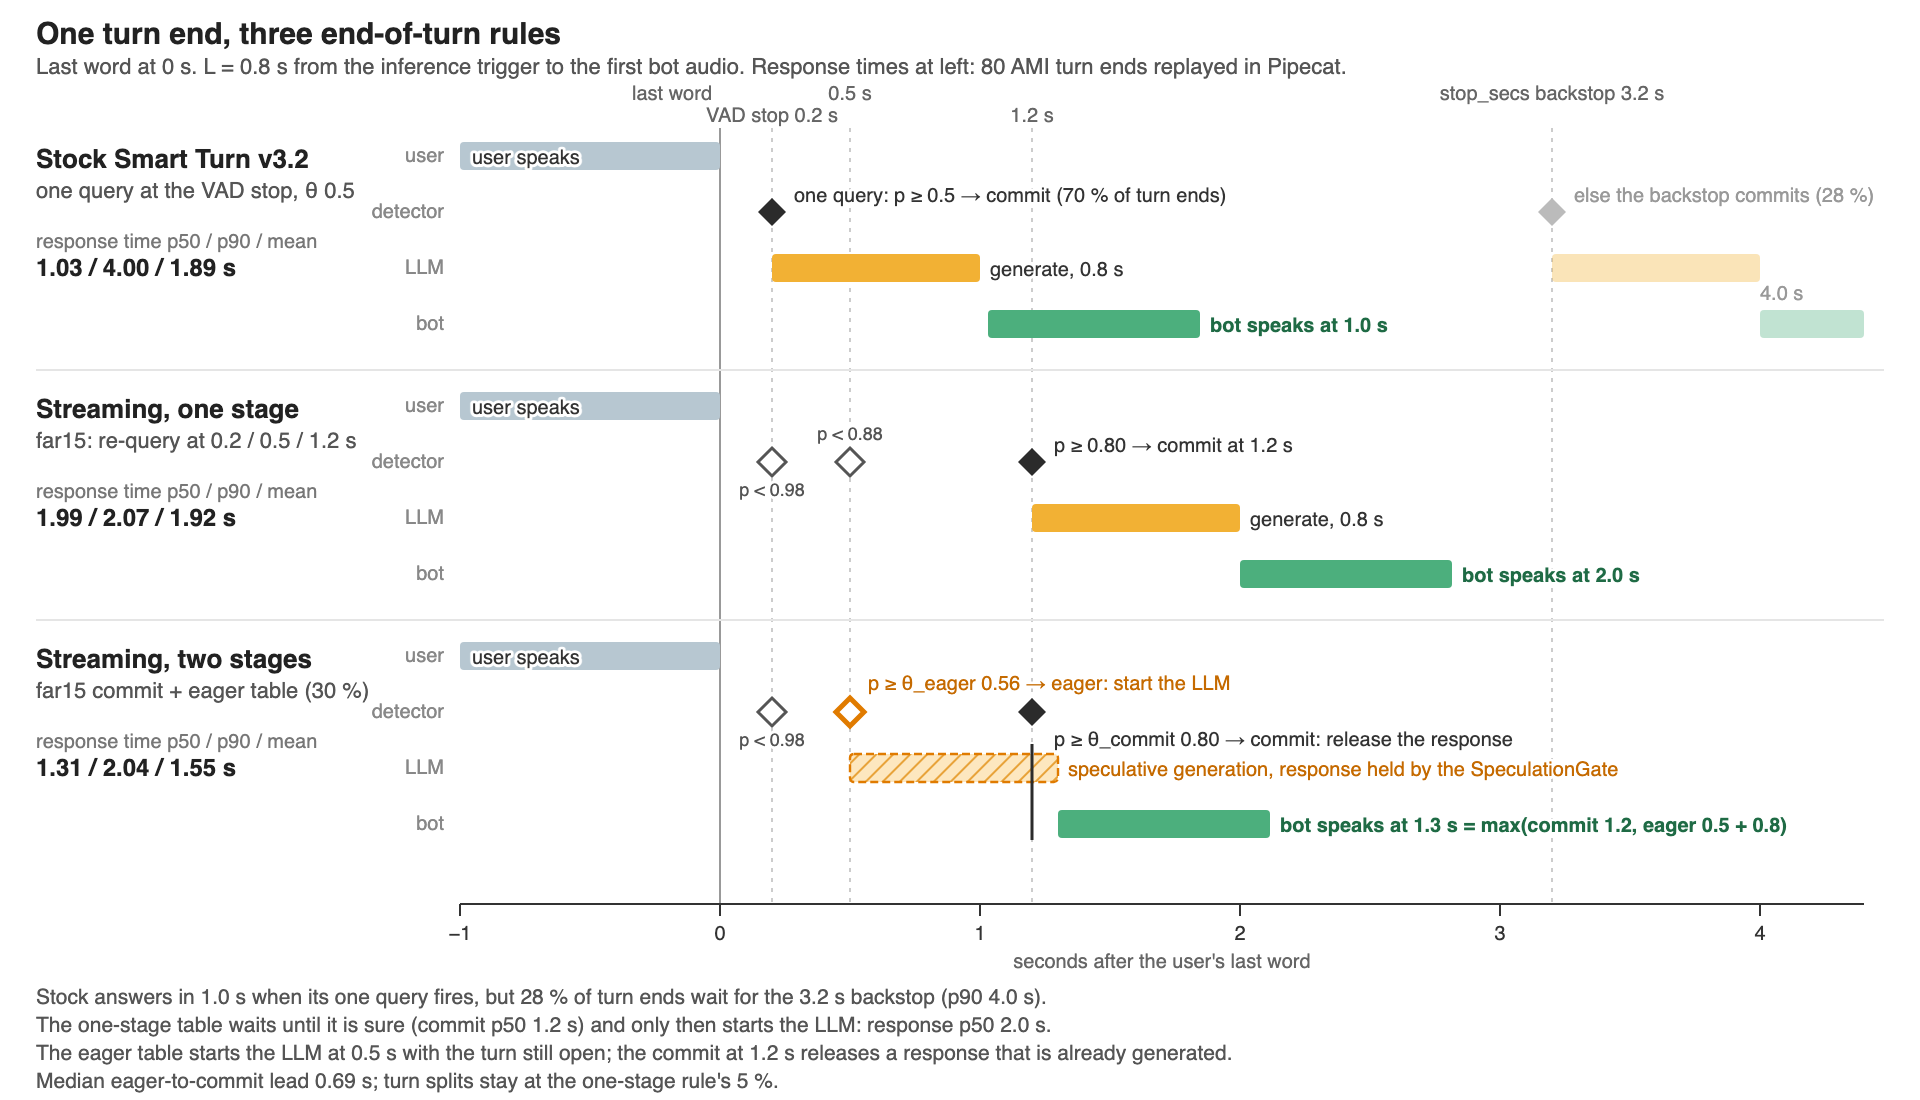
|
| 36 |
+
|
| 37 |
+
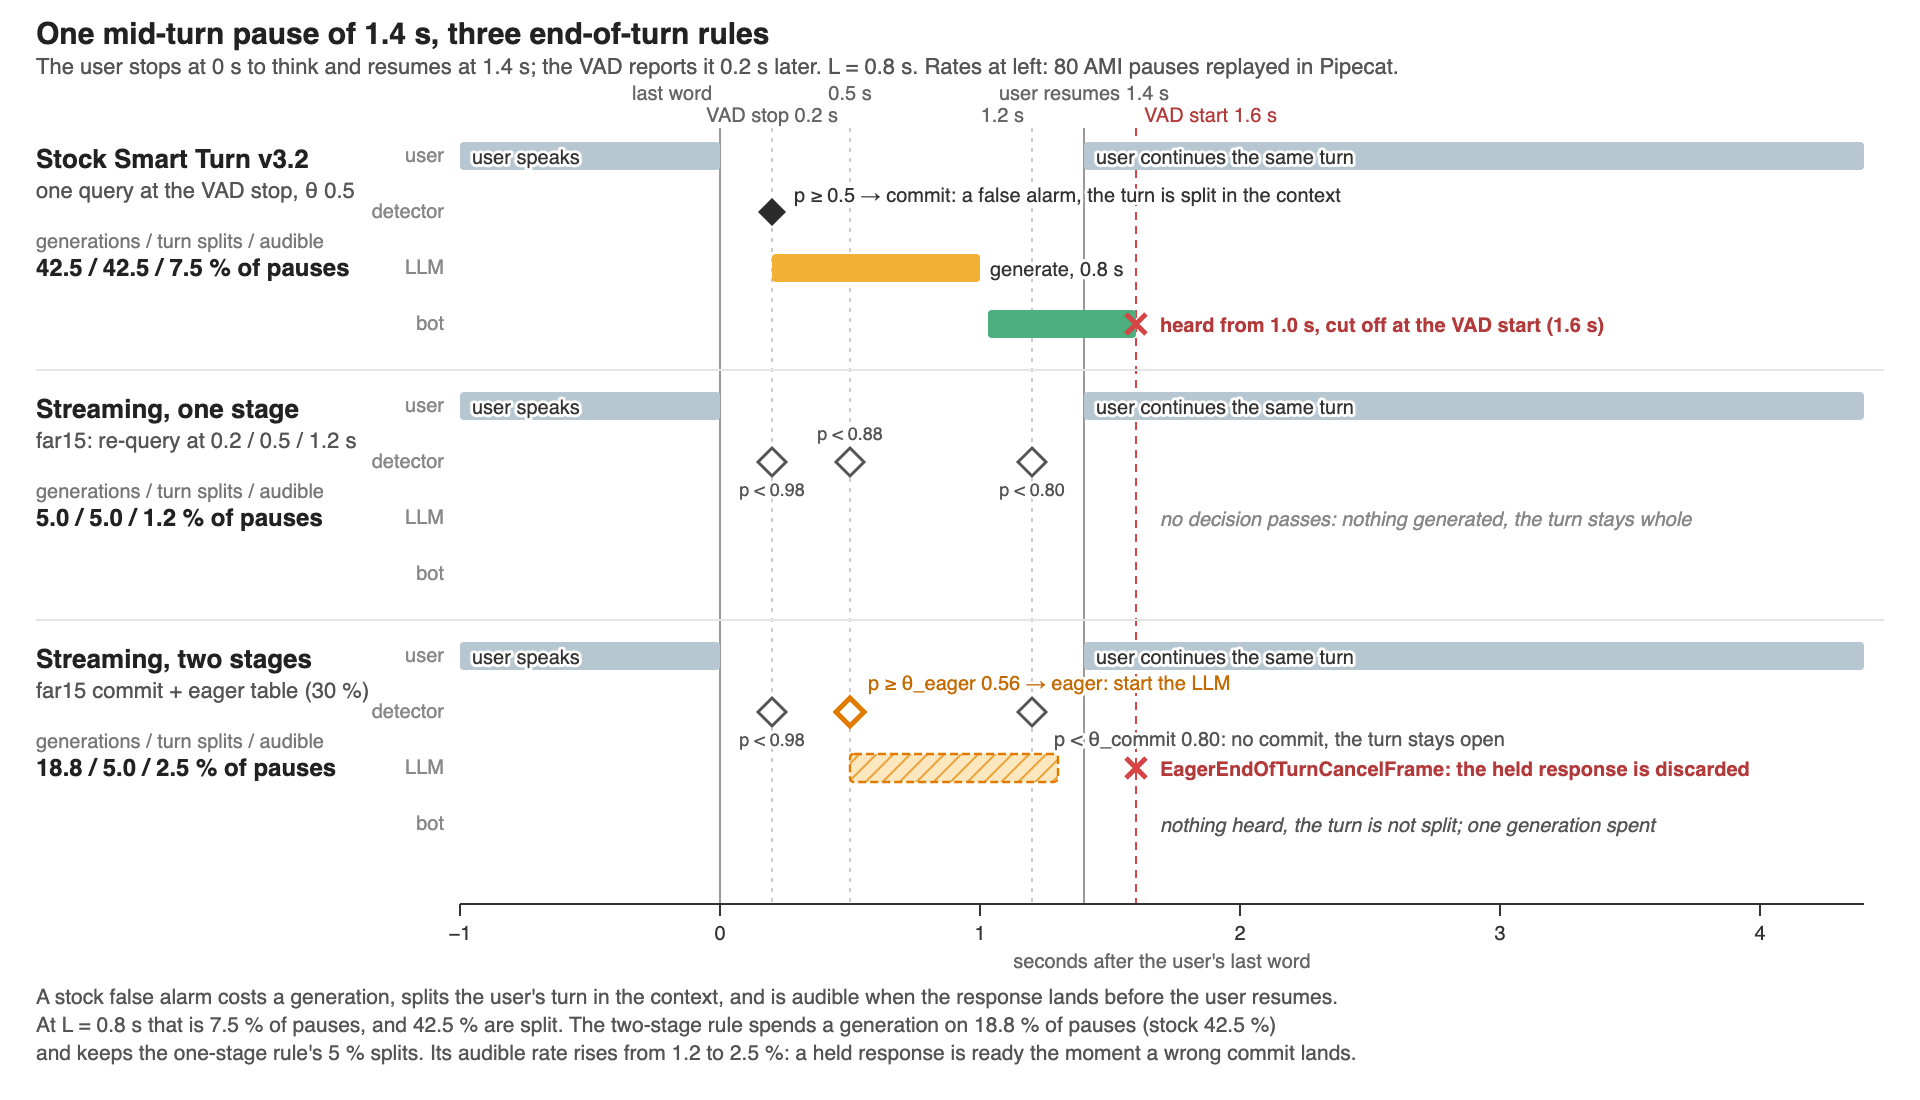
|
| 38 |
+
|
| 39 |
+
## Files
|
| 40 |
+
|
| 41 |
+
| file | size | what |
|
| 42 |
+
|---|---|---|
|
| 43 |
+
| `smart-turn-v3.2-encoder-pooled.onnx` | 31 MB | Pipecat's Smart Turn v3.2 (Whisper-tiny encoder + its classifier), weights unchanged, with the pooled 384-d vector exposed as a second output. Input `input_features` (1, 80, 800) Whisper log-mel of the last 8 s; outputs `logits` (the stock model's P(complete)) and `sum_1` (the pooled vector). |
|
| 44 |
+
| `eot-heads-v32.onnx` | 0.7 MB | The trained heads: LayerNorm + Linear on the pooled vector, a GRU over the last second of log-mel (20 × 80 at 50 ms), the silence length, a fusion MLP. Inputs `pooled` (1, 384), `mel20` (1, 20, 80), `tau_feat` (1, 3) = [τ / 2.5, log1p(τ), speaking]; output `probs` (1, 2) = [P(turn complete), P(turn ends within 0.4 s)]. 172k parameters. |
|
| 45 |
+
| `rules/theta_tables.csv` | | Commit thresholds θ(0.2 s), θ(0.5 s), θ(1.2 s) fitted on AMI dev at false-alarm budgets of 5 / 10 / 15 %, with their AMI test numbers. |
|
| 46 |
+
| `rules/eager_tables.csv` | | Eager thresholds for Pipecat's speculation path, fitted on AMI dev at budgets of LLM generations spent on pauses (20–50 %). |
|
| 47 |
+
| `eval/ami_eval.py`, `eval/ami_{dev,test}.csv`, `eval/ami_eval_reference.md` | | Reproduces the AMI tables below from the public corpus audio (numpy, onnxruntime, soundfile); the reference file is its output on 2026-10-25. |
|
| 48 |
+
| `LICENSE`, `AMI_LICENCE.txt`, `ATTRIBUTION.md` | | BSD 2-Clause for this release; CC BY 4.0 for the AMI-derived manifests; sources and citations. |
|
| 49 |
+
|
| 50 |
+
## How it works
|
| 51 |
+
|
| 52 |
+
Two cadences in one object on one CPU thread, plus one worker thread for the encoder:
|
| 53 |
+
|
| 54 |
+
| path | when | work | cost (Apple M4, 1 ORT thread) |
|
| 55 |
+
|---|---|---|---|
|
| 56 |
+
| mel | every 20 ms audio frame | incremental Whisper log-mel, one 10 ms column at a time (exact to 0.003 against the reference extractor on real audio) | 0.02 ms |
|
| 57 |
+
| heads | every 100 ms, and at each silence-clock point | last 1 s of mel → GRU, cached pooled vector, τ → P(complete) | 0.7 ms |
|
| 58 |
+
| encoder | every 320 ms while the user speaks; at τ = 0, 0.2, 0.5, 0.8, 1.2, 1.8, 2.5 s of silence (the grid the heads were trained on), where the decision waits for it | 8 s window → Whisper-tiny → pooled vector, on a worker thread | 22 ms (46 ms when the core is otherwise idle) |
|
| 59 |
+
|
| 60 |
+
The decision rule queries P(complete) at 0.2, 0.5 and 1.2 s of silence while the pause lasts and
|
| 61 |
+
commits at the first offset where it exceeds θ(offset); Pipecat's `stop_secs` (3 s) stays as the
|
| 62 |
+
backstop. The budget is the product knob: `far10` for an agent that must not interrupt, `far15` when
|
| 63 |
+
a fast reply matters more. A second, looser table (`eager_tables.csv`) on the same decision points
|
| 64 |
+
drives Pipecat's speculation path (`UserTurnSpeculation` → `SpeculationGate`): the LLM starts
|
| 65 |
+
generating at the eager point, the response is held until the commit and discarded if the user
|
| 66 |
+
resumes.
|
| 67 |
+
|
| 68 |
+
Why silence awareness has to be trained: 79 % of the clips in `smart-turn-data-v3.2` end within
|
| 69 |
+
0.2 s of the speech, so the published models never saw a pause, and their false-alarm rate on
|
| 70 |
+
incomplete utterances rises from 5 % at the offset to 19 % after 2.5 s of silence. The heads were
|
| 71 |
+
trained on windows ending τ ∈ {0 … 2.5} s after the acoustic offset (clips padded with their own
|
| 72 |
+
room tone) plus 43k real conversational pauses from AMI. The GRU over the last second of mel is the
|
| 73 |
+
component that carries the silence awareness (AUC at 1.2 s of silence 0.74 with it, 0.66 without).
|
| 74 |
+
|
| 75 |
+
## Results
|
| 76 |
+
|
| 77 |
+
### AMI Meeting Corpus, test split (511 turn ends, 4,304 mid-turn pauses, 16 meetings, 4-party)
|
| 78 |
+
|
| 79 |
+
Offline, windows ending at τ seconds of silence (`eval/ami_eval.py` reproduces this table):
|
| 80 |
+
|
| 81 |
+
| τ (s) | AUC heads | AUC frozen Smart Turn v3.2 |
|
| 82 |
+
|---|---|---|
|
| 83 |
+
| 0.2 | 0.775 | 0.671 |
|
| 84 |
+
| 0.5 | 0.776 | 0.638 |
|
| 85 |
+
| 1.2 | 0.742 | 0.575 |
|
| 86 |
+
| 2.5 | 0.735 | 0.619 |
|
| 87 |
+
|
| 88 |
+
Over three training seeds the AUC at 0.2 s is 0.78 ± 0.01 and at 1.2 s 0.73 ± 0.01.
|
| 89 |
+
|
| 90 |
+
Decision rule, thresholds fitted on AMI dev, scored on AMI test; a turn end with no commit is
|
| 91 |
+
charged the 3 s timeout:
|
| 92 |
+
|
| 93 |
+
| rule | θ at 0.2 / 0.5 / 1.2 s | recall | false alarms on pauses | mean latency | FAR on pauses ≥ 1.5 s |
|
| 94 |
+
|---|---|---|---|---|---|
|
| 95 |
+
| stock rule (one query at the VAD stop, θ 0.5), frozen v3.2 | 0.50 / – / – | 0.51 | 30.4 % | 1.56 s | 0.45 |
|
| 96 |
+
| stock rule, heads | 0.50 / – / – | 0.64 | 25.5 % | 1.21 s | 0.46 |
|
| 97 |
+
| re-query, 10 % budget, frozen v3.2 | 1.00 / 1.00 / 0.28 | 0.70 | 10.6 % | 1.74 s | 0.61 |
|
| 98 |
+
| **re-query, 10 % budget, heads (`far10`)** | 0.92 / 0.98 / 0.86 | **0.80** | **9.4 %** | **1.48 s** | 0.50 |
|
| 99 |
+
| re-query, 15 % budget, frozen v3.2 | 1.00 / 1.00 / 0.02 | 0.87 | 13.7 % | 1.44 s | 0.78 |
|
| 100 |
+
| **re-query, 15 % budget, heads (`far15`)** | 0.98 / 0.88 / 0.80 | **0.86** | **13.3 %** | **1.21 s** | 0.61 |
|
| 101 |
+
| no model: end every turn at 1.2 s of silence | – | 1.00 | 18.0 % | 1.20 s | 1.00 |
|
| 102 |
+
|
| 103 |
+
### Regression guard: `smart-turn-data-v3.2` test (6,000 clips, balanced)
|
| 104 |
+
|
| 105 |
+
| τ (s) | AUC heads / frozen v3.2 | recall at 5 % FAR, heads / frozen |
|
| 106 |
+
|---|---|---|
|
| 107 |
+
| 0.0 | 0.975 / 0.978 | 0.87 / 0.89 |
|
| 108 |
+
| 0.2 | 0.976 / 0.976 | 0.87 / 0.86 |
|
| 109 |
+
| 1.2 | 0.972 / 0.964 | 0.84 / 0.77 |
|
| 110 |
+
| 2.5 | 0.965 / 0.955 | 0.81 / 0.72 |
|
| 111 |
+
|
| 112 |
+
Per-language and per-source AUC at τ = 0.2 s is unchanged within noise. The heads are calibrated
|
| 113 |
+
differently from the frozen model (class-weighted loss), so use the fitted tables, not θ = 0.5.
|
| 114 |
+
|
| 115 |
+
### End to end in Pipecat 1.14 (real-time replay of 160 AMI test silences through Silero VAD and `UserTurnProcessor`)
|
| 116 |
+
|
| 117 |
+
| analyzer and rule | false alarms on pauses | turn ends committed by the model (not the 3 s backstop) | commit latency p50 / p90 | response time p50 / p90 / mean at 0.8 s of LLM latency | LLM generations spent on pauses |
|
| 118 |
+
|---|---|---|---|---|---|
|
| 119 |
+
| stock `LocalSmartTurnAnalyzerV3`, v3.2 fp32 | 42.5 % | 0.70 | 0.23 / 3.20 s | 1.03 / 4.00 / 1.89 s | 42.5 % |
|
| 120 |
+
| streaming, `far10` | 2.5 % | 0.78 | 1.21 / 3.00 s | 2.01 / 3.80 / 2.36 s | 2.5 % |
|
| 121 |
+
| streaming, `far15` | 5.0 % | 0.93 | 1.19 / 1.27 s | 1.99 / 2.07 / 1.92 s | 5.0 % |
|
| 122 |
+
| **streaming, `far15` + eager 30 %** | **5.0 %** | **0.93** | 1.19 / 1.26 s | **1.31 / 2.04 / 1.55 s** | 18.8 % |
|
| 123 |
+
|
| 124 |
+
With the eager stage the median response time matches the stock analyzer within 0.3 s, the p90 is
|
| 125 |
+
halved, an eighth of the user turns are split, and only 2.5 % of pauses are audibly interrupted
|
| 126 |
+
(stock: 7.5 %).
|
| 127 |
+
|
| 128 |
+
### Cost (Apple M4, single ORT thread, numpy + onnxruntime)
|
| 129 |
+
|
| 130 |
+
| | |
|
| 131 |
+
|---|---|
|
| 132 |
+
| detector share of one core, tight loop | 9.1 % (encoder refreshes included) |
|
| 133 |
+
| whole Pipecat process (Silero VAD, pipeline, analyzer) | 16–19 % of one core at real-time pace (stock analyzer: 9 %) |
|
| 134 |
+
| heads hop | 0.7 ms |
|
| 135 |
+
| encoder refresh | 22 ms (46 ms at real-time pace on an otherwise idle machine) |
|
| 136 |
+
| pipeline-task wall time per audio frame, encoder on the worker thread | p99 4–5 ms (inline: 45 ms); the 0.5 s and 1.2 s decisions 0.2 ms |
|
| 137 |
+
| resident memory added by the analyzer | +114 MB (stock: +76 MB) |
|
| 138 |
+
| model files | 32 MB |
|
| 139 |
+
|
| 140 |
+
A cloud vCPU is about 3× slower than an M4 core for this encoder (Pipecat's own figure for the same
|
| 141 |
+
architecture on Pipecat Cloud), so expect roughly 25–30 % of one vCPU for the detector alone.
|
| 142 |
+
|
| 143 |
+
## Usage
|
| 144 |
+
|
| 145 |
+
### In Pipecat (recommended)
|
| 146 |
+
|
| 147 |
+
```python
|
| 148 |
+
from eot.pipecat_analyzer import StreamingEOTAnalyzer, StreamingEOTParams
|
| 149 |
+
from eot.pipecat_eager_strategy import TurnAnalyzerEagerUserTurnStopStrategy
|
| 150 |
+
from pipecat.turns.user_turn_strategies import UserTurnStrategies
|
| 151 |
+
from pipecat.turns.user_start import VADUserTurnStartStrategy
|
| 152 |
+
|
| 153 |
+
analyzer = StreamingEOTAnalyzer(
|
| 154 |
+
encoder_onnx="smart-turn-v3.2-encoder-pooled.onnx",
|
| 155 |
+
heads_onnx="eot-heads-v32.onnx",
|
| 156 |
+
params=StreamingEOTParams.from_rule("far15", eager="far15_gen30"), # commit and eager tables
|
| 157 |
+
)
|
| 158 |
+
strategies = UserTurnStrategies(
|
| 159 |
+
start=[VADUserTurnStartStrategy()],
|
| 160 |
+
stop=[TurnAnalyzerEagerUserTurnStopStrategy(turn_analyzer=analyzer)], # or pipecat's TurnAnalyzerUserTurnStopStrategy
|
| 161 |
+
)
|
| 162 |
+
```
|
| 163 |
+
|
| 164 |
+
`eot/` is in the repository linked above; the analyzer needs 16 kHz audio and Pipecat's default VAD
|
| 165 |
+
`stop_secs` of 0.2 s. `StreamingEOTParams.from_rule("far10")` without an eager table gives the
|
| 166 |
+
one-stage rule.
|
| 167 |
+
|
| 168 |
+
### Standalone streaming (numpy + onnxruntime)
|
| 169 |
+
|
| 170 |
+
```python
|
| 171 |
+
from eot.streaming import StreamingEOT
|
| 172 |
+
|
| 173 |
+
eot = StreamingEOT("smart-turn-v3.2-encoder-pooled.onnx", "eot-heads-v32.onnx", worker=True)
|
| 174 |
+
for frame, is_speech in audio_frames(): # 20 ms float32 frames in [-1, 1] and the VAD's verdict
|
| 175 |
+
out = eot.push(frame, is_speech) # None, or {"p_end", "p_eager", "tau", "stale_s", ...} at a hop
|
| 176 |
+
if out and not out["speaking"] and out["tau"] >= 1.2 and out["p_end"] >= 0.80:
|
| 177 |
+
... # end of turn (the far15 table's 1.2 s threshold)
|
| 178 |
+
```
|
| 179 |
+
|
| 180 |
+
### One window, offline
|
| 181 |
+
|
| 182 |
+
```python
|
| 183 |
+
import numpy as np, onnxruntime as ort
|
| 184 |
+
enc = ort.InferenceSession("smart-turn-v3.2-encoder-pooled.onnx")
|
| 185 |
+
heads = ort.InferenceSession("eot-heads-v32.onnx")
|
| 186 |
+
feats = whisper_logmel(last_8_seconds) # (80, 800); eval/ami_eval.py has a numpy implementation
|
| 187 |
+
logits, pooled = enc.run(None, {"input_features": feats[None]})
|
| 188 |
+
mel20 = feats[:, -100:].reshape(80, 20, 5).mean(-1).T[None] # last 1 s at 50 ms steps
|
| 189 |
+
tau = 0.5 # seconds of silence at the window end
|
| 190 |
+
tau_feat = np.array([[tau / 2.5, np.log1p(tau), 0.0]], np.float32)
|
| 191 |
+
p_end, p_eager = heads.run(None, {"pooled": pooled, "mel20": mel20, "tau_feat": tau_feat})[0][0]
|
| 192 |
+
```
|
| 193 |
+
|
| 194 |
+
## Limitations
|
| 195 |
+
|
| 196 |
+
- **Conversational evaluation is English-only.** The silence-aware behaviour was trained and measured on
|
| 197 |
+
English meetings (AMI); the per-language check covers 23 languages but only on isolated utterances
|
| 198 |
+
(`smart-turn-data`), where the heads stay within noise of the frozen model in every language. Whether
|
| 199 |
+
the pause thresholds transfer to other languages' conversational timing is not measured.
|
| 200 |
+
- Meetings have a ceiling set by the labels: ending every turn at 1.2 s of silence
|
| 201 |
+
gives recall 1.0 at 18 % false alarms, and below that budget about a quarter of turn ends still
|
| 202 |
+
wait for the backstop, for every model tried.
|
| 203 |
+
- Long pauses (≥ 1.5 s) remain the weak spot: 50–60 % false alarms at the 10–15 % budgets.
|
| 204 |
+
- The second output (`p_eager`, "the turn ends within 0.4 s") is not usable as a free-running
|
| 205 |
+
trigger during speech (AUC 0.70 on AMI; ~22 false fires per minute of speech). The eager tables use
|
| 206 |
+
P(complete) at the silence-clock points instead.
|
| 207 |
+
- Every decision waits for an encoder refresh of its own window: the 0.2 s decision at the VAD stop for up
|
| 208 |
+
to 50 ms (`wait_s`), the 0.5 s and 1.2 s decisions for up to 80 ms (`max_defer_s`); the encoder takes
|
| 209 |
+
22–46 ms on an M4 and about 3× that on a cloud vCPU, so raise the allowances there. If the refresh is
|
| 210 |
+
late the decision uses the cached vector, up to 320 ms old, and the analyzer records the staleness of
|
| 211 |
+
every decision. With the refresh in time the streaming decisions equal the offline evaluation's within
|
| 212 |
+
0.001 AUC on AMI.
|
| 213 |
+
- Labels are by outcome, not intent: a speaker who was cut off counts as a complete turn.
|
| 214 |
+
|
| 215 |
+
## Reproduce the AMI tables
|
| 216 |
+
|
| 217 |
+
```
|
| 218 |
+
pip install numpy onnxruntime soundfile
|
| 219 |
+
python eval/ami_eval.py --audio-dir ./ami_audio # downloads 34 headset files (~3 GB), ~10 min on an M4
|
| 220 |
+
```
|
| 221 |
+
|
| 222 |
+
## Citation
|
| 223 |
+
|
| 224 |
+
If you use this model, please cite Pipecat's Smart Turn (the encoder) and the AMI Meeting Corpus
|
| 225 |
+
(`ATTRIBUTION.md`).
|
SHA256SUMS
ADDED
|
@@ -0,0 +1,12 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
8f5e4b1f7e4dfff70198bb2867f14b75f2e3afd94944334de21ac4b9712fa29e README.md
|
| 2 |
+
dd4613e925f3d6770eb3705863dc30d0cd6427456445ae533d5906bf6687ad12 LICENSE
|
| 3 |
+
d52fd9c7c19eec9f0bec3107554c10937203e261259d73b01637a61501fec7f7 AMI_LICENCE.txt
|
| 4 |
+
2418f9016f3ba767fc400e9b6732bb3b6a31c8e2c72672861a084f44a7499c87 ATTRIBUTION.md
|
| 5 |
+
c9c1d5905088965e754fcf718765c897a779658b5fdc6ae5de471eeab41c49c0 rules/theta_tables.csv
|
| 6 |
+
3a63a46477243d1ff6e7620a96aa8cde257209b40506202312f6aff139c4e5ad rules/eager_tables.csv
|
| 7 |
+
ccdfe3ad97d9ff204644c53a027610bfaf50c20b00ee991931109a016fb3e942 eval/ami_eval.py
|
| 8 |
+
9f4fb10b3f0488e5bb2faa0b3247364c68b8e074db5e77be39045008e05049cc eval/ami_dev.csv
|
| 9 |
+
77ca3e93c35c951d2cc337154d70d94ff1f9ba71e06b3d9e08cc958f0b1034a0 eval/ami_test.csv
|
| 10 |
+
8fccc07d5262daa94989fb7f5ff92a993a38038291e33c5cb217e24b8d53e4ec eval/ami_eval_reference.md
|
| 11 |
+
37e2a4fe22e1c4efaeba4df40141e422a3b96519db9160ae9134962a936ba4ea smart-turn-v3.2-encoder-pooled.onnx
|
| 12 |
+
8d5b4039c9d7c27e22e84d372c343077489f2fe291ccd67caeeb5ce45b05ce1a eot-heads-v32.onnx
|
eot-heads-v32.onnx
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:8d5b4039c9d7c27e22e84d372c343077489f2fe291ccd67caeeb5ce45b05ce1a
|
| 3 |
+
size 696344
|
eval/ami_dev.csv
ADDED
|
The diff for this file is too large to render.
See raw diff
|
|
|
eval/ami_eval.py
ADDED
|
@@ -0,0 +1,451 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
#!/usr/bin/env python3
|
| 2 |
+
"""Reproduce the AMI end-of-turn evaluation of the Smart Turn v2 streaming heads (release R1).
|
| 3 |
+
|
| 4 |
+
python ami_eval.py --audio-dir ./ami_audio # downloads the 34 test (and dev) headset files, ~3 GB
|
| 5 |
+
python ami_eval.py --audio-dir ./ami_audio --splits test --no-fit # test only, shipped thresholds, ~5 min
|
| 6 |
+
|
| 7 |
+
What it computes, from the public AMI Meeting Corpus audio and the labelled-silence manifests shipped
|
| 8 |
+
next to this script (``ami_dev.csv``, ``ami_test.csv``; CC BY 4.0, see ../ATTRIBUTION.md):
|
| 9 |
+
|
| 10 |
+
1. For every labelled silence (a VAD stop of speaker A at time ``t``) and every silence offset tau in
|
| 11 |
+
``--taus`` the 8 s window of A's headset audio ending at ``t + tau``. For complete turns the audio after
|
| 12 |
+
the next speaker's onset (``t + b_onset_s``) is replaced by A's own room tone, because a deployed
|
| 13 |
+
microphone never hears the agent's reply; for incomplete turns a window exists only while the pause is
|
| 14 |
+
still going on (``tau < gap_s``).
|
| 15 |
+
2. Whisper log-mel features (80 x 800, as ``WhisperFeatureExtractor(chunk_length=8)`` with
|
| 16 |
+
``do_normalize=True``), the frozen Smart Turn v3.2 encoder with its pooled 384-d vector exposed, and
|
| 17 |
+
the trained heads (pooled vector + last 1 s of mel + tau) -> P(complete). The frozen model's own
|
| 18 |
+
probability is kept as the baseline.
|
| 19 |
+
3. AUC (complete vs incomplete) per tau for the heads and the frozen model, and the deployed decision
|
| 20 |
+
rule: query at 0.2 / 0.5 / 1.2 s of silence while the pause lasts, commit COMPLETE at the first offset
|
| 21 |
+
with P >= theta(offset); a complete with no commit is charged the 3 s timeout. Thresholds are the
|
| 22 |
+
shipped tables (``../rules/theta_tables.csv``) and, unless ``--no-fit``, re-fitted on the dev split under
|
| 23 |
+
false-alarm budgets of 5 / 10 / 15 % (exhaustive grid, min mean latency), then scored on test.
|
| 24 |
+
|
| 25 |
+
Dependencies: numpy, onnxruntime, soundfile. CPU only; about 16k encoder windows for dev + test at the
|
| 26 |
+
three rule offsets (~7 min single-threaded on an Apple M4). Scores are cached in ``--cache`` so the
|
| 27 |
+
tables can be re-made without re-running the models.
|
| 28 |
+
"""
|
| 29 |
+
|
| 30 |
+
from __future__ import annotations
|
| 31 |
+
|
| 32 |
+
import argparse
|
| 33 |
+
import csv
|
| 34 |
+
import itertools
|
| 35 |
+
import json
|
| 36 |
+
import math
|
| 37 |
+
import os
|
| 38 |
+
import sys
|
| 39 |
+
import time
|
| 40 |
+
import urllib.request
|
| 41 |
+
from pathlib import Path
|
| 42 |
+
|
| 43 |
+
import numpy as np
|
| 44 |
+
|
| 45 |
+
SR = 16000
|
| 46 |
+
WIN_S = 8.0
|
| 47 |
+
N_FFT, HOP, N_MELS, WIN_FRAMES = 400, 160, 80, 800
|
| 48 |
+
MEL20_FRAMES, MEL20_GROUP = 100, 5
|
| 49 |
+
OFFSETS = (0.2, 0.5, 1.2)
|
| 50 |
+
TAU_GRID = (0.0, 0.1, 0.2, 0.3, 0.5, 0.8, 1.2, 1.8, 2.5)
|
| 51 |
+
TIMEOUT_S = 3.0
|
| 52 |
+
MIRROR = "https://groups.inf.ed.ac.uk/ami/AMICorpusMirror/amicorpus"
|
| 53 |
+
HERE = Path(__file__).resolve().parent
|
| 54 |
+
|
| 55 |
+
|
| 56 |
+
# --- Whisper log-mel in numpy ---------------------------------------------------------------------
|
| 57 |
+
|
| 58 |
+
def _hz_to_mel(f):
|
| 59 |
+
f = np.asarray(f, dtype=np.float64)
|
| 60 |
+
m = 3.0 * f / 200.0
|
| 61 |
+
hi = f >= 1000.0
|
| 62 |
+
m[hi] = 15.0 + np.log(f[hi] / 1000.0) * (27.0 / np.log(6.4))
|
| 63 |
+
return m
|
| 64 |
+
|
| 65 |
+
|
| 66 |
+
def _mel_to_hz(m):
|
| 67 |
+
m = np.asarray(m, dtype=np.float64)
|
| 68 |
+
f = 200.0 * m / 3.0
|
| 69 |
+
hi = m >= 15.0
|
| 70 |
+
f[hi] = 1000.0 * np.exp(np.log(6.4) / 27.0 * (m[hi] - 15.0))
|
| 71 |
+
return f
|
| 72 |
+
|
| 73 |
+
|
| 74 |
+
def mel_filters(n_freq: int = N_FFT // 2 + 1, n_mels: int = N_MELS, sr: int = SR) -> np.ndarray:
|
| 75 |
+
"""(201, 80) Slaney-normalised triangular filterbank, identical to transformers' ``mel_filter_bank``."""
|
| 76 |
+
fft_freqs = np.linspace(0.0, sr / 2, n_freq)
|
| 77 |
+
mel_pts = np.linspace(_hz_to_mel(np.array([0.0]))[0], _hz_to_mel(np.array([sr / 2]))[0], n_mels + 2)
|
| 78 |
+
f = _mel_to_hz(mel_pts)
|
| 79 |
+
d = np.diff(f)
|
| 80 |
+
slopes = f[None, :] - fft_freqs[:, None]
|
| 81 |
+
fb = np.maximum(0.0, np.minimum(-slopes[:, :-2] / d[None, :-1], slopes[:, 2:] / d[None, 1:]))
|
| 82 |
+
enorm = 2.0 / (f[2: n_mels + 2] - f[:n_mels])
|
| 83 |
+
return (fb * enorm[None, :]).astype(np.float32)
|
| 84 |
+
|
| 85 |
+
|
| 86 |
+
_FILTERS = mel_filters()
|
| 87 |
+
_WINDOW = np.hanning(N_FFT + 1)[:-1].astype(np.float32)
|
| 88 |
+
|
| 89 |
+
|
| 90 |
+
def whisper_logmel(x: np.ndarray) -> np.ndarray:
|
| 91 |
+
"""(80, 800) features of exactly 8 s of 16 kHz audio, as WhisperFeatureExtractor(chunk_length=8)
|
| 92 |
+
with padding='max_length', truncation=True, do_normalize=True gives them."""
|
| 93 |
+
x = np.asarray(x, dtype=np.float64)
|
| 94 |
+
assert len(x) == int(WIN_S * SR), len(x)
|
| 95 |
+
x = (x - x.mean()) / np.sqrt(x.var() + 1e-7) # do_normalize
|
| 96 |
+
pad = N_FFT // 2
|
| 97 |
+
xp = np.concatenate([x[1: pad + 1][::-1], x, x[-pad - 1: -1][::-1]]) # reflect padding, centre=True
|
| 98 |
+
n_frames = 1 + (len(xp) - N_FFT) // HOP # 801; the last one is dropped
|
| 99 |
+
idx = np.arange(N_FFT)[None, :] + HOP * np.arange(n_frames)[:, None]
|
| 100 |
+
frames = xp[idx] * _WINDOW
|
| 101 |
+
spec = np.abs(np.fft.rfft(frames, axis=1)) ** 2 # (801, 201)
|
| 102 |
+
mel = spec[:-1] @ _FILTERS # (800, 80)
|
| 103 |
+
ls = np.log10(np.maximum(mel, 1e-10))
|
| 104 |
+
ls = np.maximum(ls, ls.max() - 8.0)
|
| 105 |
+
return ((ls + 4.0) / 4.0).T.astype(np.float32)
|
| 106 |
+
|
| 107 |
+
|
| 108 |
+
def mel20(feats: np.ndarray) -> np.ndarray:
|
| 109 |
+
"""(20, 80): the last second of the features averaged to 50 ms steps (the heads' fresh-mel input)."""
|
| 110 |
+
return feats[:, -MEL20_FRAMES:].reshape(N_MELS, MEL20_FRAMES // MEL20_GROUP, MEL20_GROUP).mean(-1).T.astype(np.float32)
|
| 111 |
+
|
| 112 |
+
|
| 113 |
+
# --- windows ----------------------------------------------------------------------------------------
|
| 114 |
+
|
| 115 |
+
def room_tone(x: np.ndarray, sr: int, t_off: float, n: int, rng: np.random.Generator) -> np.ndarray:
|
| 116 |
+
"""``n`` samples of room tone tiled from the audio after ``t_off`` (0.5 s tiles, random order, some
|
| 117 |
+
reversed, 10 ms crossfades), as the training windows were built."""
|
| 118 |
+
tail = x[int(round(t_off * sr)):]
|
| 119 |
+
if n <= 0:
|
| 120 |
+
return np.zeros(0, np.float32)
|
| 121 |
+
if len(tail) < int(0.05 * sr):
|
| 122 |
+
nf = len(x) // 320
|
| 123 |
+
if nf >= 5:
|
| 124 |
+
fr = x[: nf * 320].reshape(nf, 320).astype(np.float64)
|
| 125 |
+
level = float(np.percentile(np.sqrt(np.mean(fr * fr, axis=1)), 5))
|
| 126 |
+
else:
|
| 127 |
+
level = float(np.sqrt(np.mean(np.square(x, dtype=np.float64)))) if len(x) else 0.0
|
| 128 |
+
level = float(np.clip(level, 10 ** (-70 / 20), 10 ** (-45 / 20)))
|
| 129 |
+
return (rng.standard_normal(n) * level).astype(np.float32)
|
| 130 |
+
fade = int(10 * sr / 1000)
|
| 131 |
+
tile = min(len(tail), int(0.5 * sr))
|
| 132 |
+
out = np.zeros(n + tile, np.float32)
|
| 133 |
+
ramp = np.linspace(0.0, 1.0, fade, dtype=np.float32)
|
| 134 |
+
pos = 0
|
| 135 |
+
while pos < n:
|
| 136 |
+
start = int(rng.integers(0, len(tail) - tile + 1))
|
| 137 |
+
seg = tail[start: start + tile].copy()
|
| 138 |
+
if rng.random() < 0.5:
|
| 139 |
+
seg = seg[::-1]
|
| 140 |
+
if pos > 0 and tile > fade:
|
| 141 |
+
seg[:fade] *= ramp
|
| 142 |
+
out[pos - fade: pos] *= ramp[::-1]
|
| 143 |
+
out[pos - fade: pos - fade + tile] += seg
|
| 144 |
+
pos += tile - fade
|
| 145 |
+
else:
|
| 146 |
+
out[pos: pos + tile] = seg
|
| 147 |
+
pos += tile
|
| 148 |
+
return out[:n]
|
| 149 |
+
|
| 150 |
+
|
| 151 |
+
def cut_window(x: np.ndarray, end_s: float, t_off: float, cut_s: float | None, rng: np.random.Generator) -> np.ndarray:
|
| 152 |
+
"""8 s ending at ``end_s``: zeros before the recording, A's room tone after ``cut_s`` (the next
|
| 153 |
+
speaker's onset) or after the end of the recording."""
|
| 154 |
+
if cut_s is not None:
|
| 155 |
+
x = x[: int(round(cut_s * SR))]
|
| 156 |
+
n = int(WIN_S * SR)
|
| 157 |
+
end = int(round(end_s * SR))
|
| 158 |
+
start = end - n
|
| 159 |
+
out = np.zeros(n, np.float32)
|
| 160 |
+
s0, s1 = max(start, 0), min(end, len(x))
|
| 161 |
+
if s1 > s0:
|
| 162 |
+
out[s0 - start: s1 - start] = x[s0:s1]
|
| 163 |
+
if end > len(x):
|
| 164 |
+
pad_from = max(len(x), start)
|
| 165 |
+
out[pad_from - start:] = room_tone(x, SR, t_off, end - pad_from, rng)
|
| 166 |
+
return out
|
| 167 |
+
|
| 168 |
+
|
| 169 |
+
# --- data -------------------------------------------------------------------------------------------
|
| 170 |
+
|
| 171 |
+
def read_manifest(path: Path) -> list[dict]:
|
| 172 |
+
rows = []
|
| 173 |
+
with open(path, newline="") as f:
|
| 174 |
+
for r in csv.DictReader(f):
|
| 175 |
+
rows.append(dict(meeting=r["meeting"], speaker=r["speaker"], channel=int(r["channel"]), t=float(r["t"]),
|
| 176 |
+
label=int(r["label"] == "complete"),
|
| 177 |
+
gap_s=float(r["gap_s"]) if r["gap_s"] else math.nan,
|
| 178 |
+
b_onset_s=float(r["b_onset_s"]) if r["b_onset_s"] else math.nan))
|
| 179 |
+
return rows
|
| 180 |
+
|
| 181 |
+
|
| 182 |
+
def headset_path(audio_dir: Path, meeting: str, channel: int) -> Path:
|
| 183 |
+
return audio_dir / meeting / f"{meeting}.Headset-{channel}.wav"
|
| 184 |
+
|
| 185 |
+
|
| 186 |
+
def fetch_audio(audio_dir: Path, rows: list[dict], retries: int = 4) -> None:
|
| 187 |
+
need = sorted({(r["meeting"], r["channel"]) for r in rows})
|
| 188 |
+
missing = [(m, c) for m, c in need if not headset_path(audio_dir, m, c).exists()]
|
| 189 |
+
if not missing:
|
| 190 |
+
return
|
| 191 |
+
print(f"downloading {len(missing)} headset files (~40 MB each) from {MIRROR} into {audio_dir}", flush=True)
|
| 192 |
+
for m, c in missing:
|
| 193 |
+
url = f"{MIRROR}/{m}/audio/{m}.Headset-{c}.wav"
|
| 194 |
+
dest = headset_path(audio_dir, m, c)
|
| 195 |
+
dest.parent.mkdir(parents=True, exist_ok=True)
|
| 196 |
+
for attempt in range(retries):
|
| 197 |
+
try:
|
| 198 |
+
tmp = dest.with_suffix(".part")
|
| 199 |
+
with urllib.request.urlopen(url, timeout=120) as r, open(tmp, "wb") as f:
|
| 200 |
+
size = int(r.headers.get("Content-Length", "0"))
|
| 201 |
+
while True:
|
| 202 |
+
chunk = r.read(1 << 20)
|
| 203 |
+
if not chunk:
|
| 204 |
+
break
|
| 205 |
+
f.write(chunk)
|
| 206 |
+
if size and tmp.stat().st_size != size:
|
| 207 |
+
raise OSError(f"size mismatch {tmp.stat().st_size} != {size}")
|
| 208 |
+
tmp.replace(dest)
|
| 209 |
+
print(f" got {dest.name}", flush=True)
|
| 210 |
+
break
|
| 211 |
+
except Exception as e: # noqa: BLE001
|
| 212 |
+
if attempt == retries - 1:
|
| 213 |
+
raise
|
| 214 |
+
print(f" retry {dest.name}: {e}", flush=True)
|
| 215 |
+
time.sleep(5 * (attempt + 1))
|
| 216 |
+
|
| 217 |
+
|
| 218 |
+
# --- models -----------------------------------------------------------------------------------------
|
| 219 |
+
|
| 220 |
+
class Models:
|
| 221 |
+
def __init__(self, encoder: Path, heads: Path, threads: int):
|
| 222 |
+
import onnxruntime as ort
|
| 223 |
+
so = ort.SessionOptions()
|
| 224 |
+
so.intra_op_num_threads = threads
|
| 225 |
+
so.graph_optimization_level = ort.GraphOptimizationLevel.ORT_ENABLE_ALL
|
| 226 |
+
self.enc = ort.InferenceSession(str(encoder), sess_options=so, providers=["CPUExecutionProvider"])
|
| 227 |
+
self.heads = ort.InferenceSession(str(heads), sess_options=so, providers=["CPUExecutionProvider"])
|
| 228 |
+
self.enc_in = self.enc.get_inputs()[0].name
|
| 229 |
+
outs = [o.name for o in self.enc.get_outputs()]
|
| 230 |
+
self.enc_prob, self.enc_pooled = outs[0], outs[-1]
|
| 231 |
+
|
| 232 |
+
def score(self, feats: np.ndarray, taus: np.ndarray) -> tuple[np.ndarray, np.ndarray]:
|
| 233 |
+
"""feats (B, 80, 800), taus (B,) -> (p_end of the heads (B,), p of the frozen model (B,))."""
|
| 234 |
+
prob, pooled = self.enc.run([self.enc_prob, self.enc_pooled], {self.enc_in: feats.astype(np.float32)})
|
| 235 |
+
m20 = np.stack([mel20(f) for f in feats])
|
| 236 |
+
tau_feat = np.stack([taus / 2.5, np.log1p(taus), np.zeros_like(taus)], axis=1).astype(np.float32)
|
| 237 |
+
p = self.heads.run(None, {"pooled": pooled.astype(np.float32), "mel20": m20, "tau_feat": tau_feat})[0]
|
| 238 |
+
return p[:, 0].astype(np.float64), prob.reshape(-1).astype(np.float64)
|
| 239 |
+
|
| 240 |
+
|
| 241 |
+
def score_split(rows: list[dict], taus: tuple, models: Models, audio_dir: Path, seed: int, batch: int = 16, tag: str = "") -> dict:
|
| 242 |
+
"""Per silence and tau: P(complete) of the heads and of the frozen model (nan where no window)."""
|
| 243 |
+
rng = np.random.default_rng(seed)
|
| 244 |
+
P = np.full((len(rows), len(taus)), np.nan)
|
| 245 |
+
PB = np.full((len(rows), len(taus)), np.nan)
|
| 246 |
+
import soundfile as sf
|
| 247 |
+
by_file: dict[tuple, list[int]] = {}
|
| 248 |
+
for i, r in enumerate(rows):
|
| 249 |
+
by_file.setdefault((r["meeting"], r["channel"]), []).append(i)
|
| 250 |
+
jobs = [] # (row index, tau index, window)
|
| 251 |
+
t0, done, total = time.time(), 0, sum(len(v) for v in by_file.values())
|
| 252 |
+
|
| 253 |
+
def flush():
|
| 254 |
+
if not jobs:
|
| 255 |
+
return
|
| 256 |
+
feats = np.stack([whisper_logmel(w) for _, _, w in jobs])
|
| 257 |
+
p, pb = models.score(feats, np.array([taus[k] for _, k, _ in jobs], np.float64))
|
| 258 |
+
for (i, k, _), a, b in zip(jobs, p, pb):
|
| 259 |
+
P[i, k], PB[i, k] = a, b
|
| 260 |
+
jobs.clear()
|
| 261 |
+
|
| 262 |
+
for (meeting, channel), idx in by_file.items():
|
| 263 |
+
x, sr = sf.read(headset_path(audio_dir, meeting, channel), dtype="float32")
|
| 264 |
+
if sr != SR:
|
| 265 |
+
raise ValueError(f"{meeting} headset {channel}: {sr} Hz, expected 16 kHz")
|
| 266 |
+
if x.ndim > 1:
|
| 267 |
+
x = x[:, 0]
|
| 268 |
+
for i in idx:
|
| 269 |
+
r = rows[i]
|
| 270 |
+
for k, tau in enumerate(taus):
|
| 271 |
+
if not r["label"] and not (tau < r["gap_s"]):
|
| 272 |
+
continue # the pause ended before this offset
|
| 273 |
+
cut = r["t"] + r["b_onset_s"] if (r["label"] and not math.isnan(r["b_onset_s"]) and tau > r["b_onset_s"]) else None
|
| 274 |
+
jobs.append((i, k, cut_window(x, r["t"] + tau, r["t"], cut, rng)))
|
| 275 |
+
if len(jobs) >= batch:
|
| 276 |
+
flush()
|
| 277 |
+
done += len(idx)
|
| 278 |
+
print(f" {tag}{done}/{total} silences, {time.time() - t0:.0f} s", end="\r", file=sys.stderr, flush=True)
|
| 279 |
+
flush()
|
| 280 |
+
print(file=sys.stderr)
|
| 281 |
+
return dict(p=P, pb=PB, label=np.array([r["label"] for r in rows]), gap=np.array([r["gap_s"] for r in rows]), taus=np.array(taus))
|
| 282 |
+
|
| 283 |
+
|
| 284 |
+
# --- metrics ----------------------------------------------------------------------------------------
|
| 285 |
+
|
| 286 |
+
def auc(y: np.ndarray, s: np.ndarray) -> float:
|
| 287 |
+
"""ROC AUC by the rank statistic (ties counted half)."""
|
| 288 |
+
y, s = np.asarray(y), np.asarray(s)
|
| 289 |
+
pos, neg = s[y == 1], s[y == 0]
|
| 290 |
+
if not len(pos) or not len(neg):
|
| 291 |
+
return math.nan
|
| 292 |
+
order = np.argsort(np.concatenate([pos, neg]), kind="mergesort")
|
| 293 |
+
ranks = np.empty(len(order)); ranks[order] = np.arange(1, len(order) + 1)
|
| 294 |
+
allv = np.concatenate([pos, neg])
|
| 295 |
+
# average ranks for ties
|
| 296 |
+
uniq, inv, counts = np.unique(allv, return_inverse=True, return_counts=True)
|
| 297 |
+
sums = np.bincount(inv, weights=ranks)
|
| 298 |
+
ranks = (sums / counts)[inv]
|
| 299 |
+
return float((ranks[: len(pos)].sum() - len(pos) * (len(pos) + 1) / 2) / (len(pos) * len(neg)))
|
| 300 |
+
|
| 301 |
+
|
| 302 |
+
def simulate(p, avail, label, gap, theta, offsets=OFFSETS) -> dict:
|
| 303 |
+
th = np.asarray(theta)[None, :]
|
| 304 |
+
hit = avail & (np.nan_to_num(p, nan=-1.0) >= th)
|
| 305 |
+
first = np.where(hit.any(1), hit.argmax(1), -1)
|
| 306 |
+
comp, inc = label == 1, label == 0
|
| 307 |
+
lat = np.full(comp.sum(), TIMEOUT_S)
|
| 308 |
+
ok = first[comp] >= 0
|
| 309 |
+
lat[ok] = np.asarray(offsets)[first[comp][ok]]
|
| 310 |
+
fa = first[inc] >= 0
|
| 311 |
+
bins = {"<0.5": gap[inc] < 0.5, "0.5-1.5": (gap[inc] >= 0.5) & (gap[inc] < 1.5), ">=1.5": gap[inc] >= 1.5}
|
| 312 |
+
return dict(theta=tuple(float(t) for t in theta), recall=float(ok.mean()), far=float(fa.mean()),
|
| 313 |
+
p50=float(np.percentile(lat, 50)), p90=float(np.percentile(lat, 90)), mean=float(lat.mean()),
|
| 314 |
+
far_by_bin={k: (float(fa[m].mean()) if m.any() else math.nan) for k, m in bins.items()},
|
| 315 |
+
n_complete=int(comp.sum()), n_incomplete=int(inc.sum()))
|
| 316 |
+
|
| 317 |
+
|
| 318 |
+
def fit(p, avail, label, gap, target_far: float, offsets=OFFSETS, grid=np.round(np.arange(0.0, 1.0001, 0.02), 2)) -> dict:
|
| 319 |
+
"""Exhaustive grid over theta per offset with FAR <= target, minimising the mean latency (misses charged 3 s)."""
|
| 320 |
+
inc, comp = label == 0, label == 1
|
| 321 |
+
K = len(offsets)
|
| 322 |
+
hits = [np.stack([avail[:, k] & (np.nan_to_num(p[:, k], nan=-1.0) >= t) for t in grid]) for k in range(K)]
|
| 323 |
+
best = None
|
| 324 |
+
for combo in itertools.product(range(len(grid)), repeat=K):
|
| 325 |
+
h = np.stack([hits[k][combo[k]] for k in range(K)], axis=1)
|
| 326 |
+
first = np.where(h.any(1), h.argmax(1), -1)
|
| 327 |
+
if (first[inc] >= 0).mean() > target_far:
|
| 328 |
+
continue
|
| 329 |
+
rec = (first[comp] >= 0).mean()
|
| 330 |
+
lat = np.where(first[comp] >= 0, np.asarray(offsets)[np.maximum(first[comp], 0)], TIMEOUT_S).mean()
|
| 331 |
+
key = (lat, -rec)
|
| 332 |
+
if best is None or key < best[0]:
|
| 333 |
+
best = (key, tuple(grid[i] for i in combo))
|
| 334 |
+
theta = best[1] if best else tuple([1.01] * K)
|
| 335 |
+
return simulate(p, avail, label, gap, theta, offsets)
|
| 336 |
+
|
| 337 |
+
|
| 338 |
+
def rule_inputs(sc: dict, offsets=OFFSETS):
|
| 339 |
+
cols = [int(np.where(np.isclose(sc["taus"], o))[0][0]) for o in offsets]
|
| 340 |
+
p, pb = sc["p"][:, cols], sc["pb"][:, cols]
|
| 341 |
+
label, gap = sc["label"], sc["gap"]
|
| 342 |
+
avail = (label[:, None] == 1) | (np.nan_to_num(gap, nan=np.inf)[:, None] > np.asarray(offsets)[None, :])
|
| 343 |
+
avail &= ~np.isnan(p)
|
| 344 |
+
# the rule is scored on silences that have a decision point before the resumption
|
| 345 |
+
keep = avail.any(1)
|
| 346 |
+
return p[keep], pb[keep], avail[keep], label[keep], gap[keep]
|
| 347 |
+
|
| 348 |
+
|
| 349 |
+
def rule_row(name: str, r: dict) -> str:
|
| 350 |
+
th = " / ".join(f"{t:.2f}" if t <= 1 else "-" for t in r["theta"])
|
| 351 |
+
fb = " / ".join(f"{r['far_by_bin'][k]:.2f}" for k in ("<0.5", "0.5-1.5", ">=1.5"))
|
| 352 |
+
return f"| {name} | {th} | {r['recall']:.2f} | {r['far']:.3f} | {r['p50']:.2f} s | {r['p90']:.2f} s | {r['mean']:.2f} s | {fb} |"
|
| 353 |
+
|
| 354 |
+
|
| 355 |
+
def read_theta_tables(path: Path) -> list[tuple[str, tuple]]:
|
| 356 |
+
out = []
|
| 357 |
+
if not path.exists():
|
| 358 |
+
return out
|
| 359 |
+
with open(path, newline="") as f:
|
| 360 |
+
for r in csv.DictReader(f):
|
| 361 |
+
if r["model"] == "heads":
|
| 362 |
+
out.append((f"shipped table, {float(r['far_budget']):.0%} budget", tuple(float(t) for t in json.loads(r["theta"].replace("(", "[").replace(")", "]")))))
|
| 363 |
+
return out
|
| 364 |
+
|
| 365 |
+
|
| 366 |
+
# --- main -------------------------------------------------------------------------------------------
|
| 367 |
+
|
| 368 |
+
def main():
|
| 369 |
+
ap = argparse.ArgumentParser(description=__doc__, formatter_class=argparse.RawDescriptionHelpFormatter)
|
| 370 |
+
ap.add_argument("--audio-dir", default="./ami_audio", help="AMI headset audio, <meeting>/<meeting>.Headset-<n>.wav (downloaded when missing)")
|
| 371 |
+
ap.add_argument("--no-download", action="store_true")
|
| 372 |
+
ap.add_argument("--manifest-dir", default=str(HERE), help="directory with ami_dev.csv / ami_test.csv")
|
| 373 |
+
ap.add_argument("--encoder", default=str(HERE.parent / "smart-turn-v3.2-encoder-pooled.onnx"))
|
| 374 |
+
ap.add_argument("--heads", default=str(HERE.parent / "eot-heads-v32.onnx"))
|
| 375 |
+
ap.add_argument("--theta-tables", default=str(HERE.parent / "rules" / "theta_tables.csv"))
|
| 376 |
+
ap.add_argument("--splits", nargs="*", default=["dev", "test"])
|
| 377 |
+
ap.add_argument("--taus", nargs="*", default=None, help="silence offsets to score (default: the rule offsets 0.2 0.5 1.2; 'all' = the trained grid)")
|
| 378 |
+
ap.add_argument("--budgets", nargs="*", type=float, default=[0.05, 0.10, 0.15])
|
| 379 |
+
ap.add_argument("--no-fit", action="store_true", help="skip the threshold fit on dev (score the shipped tables only)")
|
| 380 |
+
ap.add_argument("--threads", type=int, default=1)
|
| 381 |
+
ap.add_argument("--seed", type=int, default=0)
|
| 382 |
+
ap.add_argument("--cache", default="./ami_eval_scores.npz")
|
| 383 |
+
ap.add_argument("--out", default="./ami_eval.md")
|
| 384 |
+
a = ap.parse_args()
|
| 385 |
+
|
| 386 |
+
taus = TAU_GRID if (a.taus and a.taus[0] == "all") else tuple(float(t) for t in (a.taus or OFFSETS))
|
| 387 |
+
for o in OFFSETS:
|
| 388 |
+
if not any(np.isclose(o, taus)):
|
| 389 |
+
sys.exit(f"--taus must include the rule offsets {OFFSETS}")
|
| 390 |
+
audio_dir = Path(a.audio_dir)
|
| 391 |
+
rows = {sp: read_manifest(Path(a.manifest_dir) / f"ami_{sp}.csv") for sp in a.splits}
|
| 392 |
+
if not a.no_download:
|
| 393 |
+
fetch_audio(audio_dir, [r for rs in rows.values() for r in rs])
|
| 394 |
+
|
| 395 |
+
cache = dict(np.load(a.cache, allow_pickle=True)) if os.path.exists(a.cache) else {}
|
| 396 |
+
scores = {}
|
| 397 |
+
models = None
|
| 398 |
+
for sp in a.splits:
|
| 399 |
+
key = f"{sp}:{','.join(f'{t:g}' for t in taus)}:{a.seed}"
|
| 400 |
+
if key in cache:
|
| 401 |
+
scores[sp] = cache[key].item()
|
| 402 |
+
print(f"{sp}: scores from {a.cache}", file=sys.stderr)
|
| 403 |
+
continue
|
| 404 |
+
if models is None:
|
| 405 |
+
models = Models(Path(a.encoder), Path(a.heads), a.threads)
|
| 406 |
+
print(f"{sp}: scoring {len(rows[sp])} silences at tau = {taus}", file=sys.stderr, flush=True)
|
| 407 |
+
scores[sp] = score_split(rows[sp], taus, models, audio_dir, a.seed, tag=f"{sp} ")
|
| 408 |
+
cache[key] = np.array(scores[sp], dtype=object)
|
| 409 |
+
np.savez(a.cache, **cache)
|
| 410 |
+
|
| 411 |
+
lines = [f"# AMI end-of-turn evaluation ({', '.join(a.splits)}; thresholds {'shipped' if a.no_fit else 'shipped and re-fitted on dev'})", ""]
|
| 412 |
+
for sp in a.splits:
|
| 413 |
+
sc = scores[sp]
|
| 414 |
+
lines += [f"## AMI {sp}: AUC of P(complete) per silence offset", "",
|
| 415 |
+
"| tau (s) | n complete / incomplete | AUC heads | AUC frozen Smart Turn v3.2 | mean P on incompletes: heads / frozen |", "|---|---|---|---|---|"]
|
| 416 |
+
for k, tau in enumerate(sc["taus"]):
|
| 417 |
+
ok = ~np.isnan(sc["p"][:, k])
|
| 418 |
+
y, p, pb = sc["label"][ok], sc["p"][ok, k], sc["pb"][ok, k]
|
| 419 |
+
lines.append(f"| {tau:g} | {int((y == 1).sum())} / {int((y == 0).sum())} | {auc(y, p):.3f} | {auc(y, pb):.3f} | "
|
| 420 |
+
f"{p[y == 0].mean():.3f} / {pb[y == 0].mean():.3f} |")
|
| 421 |
+
lines.append("")
|
| 422 |
+
test_sp = "test" if "test" in scores else a.splits[-1]
|
| 423 |
+
P, PB, A, L, G = rule_inputs(scores[test_sp])
|
| 424 |
+
hdr = ["| rule | theta at 0.2 / 0.5 / 1.2 s | recall | FAR | p50 | p90 | mean latency | FAR by pause length <0.5 / 0.5-1.5 / >=1.5 s |",
|
| 425 |
+
"|---|---|---|---|---|---|---|---|"]
|
| 426 |
+
lines += [f"## Decision rule on AMI {test_sp} ({int((L == 1).sum())} complete / {int((L == 0).sum())} incomplete silences with a decision point; "
|
| 427 |
+
f"misses charged {TIMEOUT_S:g} s)", "", "**Heads (this release)**", ""] + hdr
|
| 428 |
+
lines.append(rule_row("one-shot at the VAD stop, theta 0.5 (stock rule)", simulate(P, A, L, G, (0.5, 1.01, 1.01))))
|
| 429 |
+
for name, th in read_theta_tables(Path(a.theta_tables)):
|
| 430 |
+
lines.append(rule_row(name, simulate(P, A, L, G, th)))
|
| 431 |
+
fitted = {}
|
| 432 |
+
if not a.no_fit and "dev" in scores:
|
| 433 |
+
Pd, PBd, Ad, Ld, Gd = rule_inputs(scores["dev"])
|
| 434 |
+
for b in a.budgets:
|
| 435 |
+
t_fit = time.time()
|
| 436 |
+
fitted[b] = (fit(Pd, Ad, Ld, Gd, b), fit(PBd, Ad, Ld, Gd, b))
|
| 437 |
+
print(f"fit at {b:.0%}: {time.time() - t_fit:.0f} s", file=sys.stderr)
|
| 438 |
+
lines.append(rule_row(f"re-fitted on dev, {b:.0%} budget", simulate(P, A, L, G, fitted[b][0]["theta"])))
|
| 439 |
+
lines += ["", "**Frozen Smart Turn v3.2 (baseline, same protocol)**", ""] + hdr
|
| 440 |
+
lines.append(rule_row("one-shot at the VAD stop, theta 0.5 (stock rule)", simulate(PB, A, L, G, (0.5, 1.01, 1.01))))
|
| 441 |
+
for b, (_, rb) in fitted.items():
|
| 442 |
+
lines.append(rule_row(f"re-fitted on dev, {b:.0%} budget", simulate(PB, A, L, G, rb["theta"])))
|
| 443 |
+
lines += ["", "**No model**", ""] + hdr
|
| 444 |
+
lines.append(rule_row("silence only, commit at 1.2 s", simulate(np.ones_like(P), A, L, G, (1.01, 1.01, 0.0))))
|
| 445 |
+
lines += ["", f"Scores cached in `{a.cache}`; audio from {MIRROR} (AMI Meeting Corpus, CC BY 4.0)."]
|
| 446 |
+
Path(a.out).write_text("\n".join(lines) + "\n")
|
| 447 |
+
print("\n".join(lines))
|
| 448 |
+
|
| 449 |
+
|
| 450 |
+
if __name__ == "__main__":
|
| 451 |
+
main()
|
eval/ami_eval_reference.md
ADDED
|
@@ -0,0 +1,48 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# AMI end-of-turn evaluation (dev, test; thresholds shipped and re-fitted on dev)
|
| 2 |
+
|
| 3 |
+
## AMI dev: AUC of P(complete) per silence offset
|
| 4 |
+
|
| 5 |
+
| tau (s) | n complete / incomplete | AUC heads | AUC frozen Smart Turn v3.2 | mean P on incompletes: heads / frozen |
|
| 6 |
+
|---|---|---|---|---|
|
| 7 |
+
| 0.2 | 734 / 3195 | 0.748 | 0.675 | 0.251 / 0.299 |
|
| 8 |
+
| 0.5 | 734 / 1827 | 0.722 | 0.640 | 0.398 / 0.414 |
|
| 9 |
+
| 1.2 | 734 / 624 | 0.698 | 0.616 | 0.727 / 0.450 |
|
| 10 |
+
|
| 11 |
+
## AMI test: AUC of P(complete) per silence offset
|
| 12 |
+
|
| 13 |
+
| tau (s) | n complete / incomplete | AUC heads | AUC frozen Smart Turn v3.2 | mean P on incompletes: heads / frozen |
|
| 14 |
+
|---|---|---|---|---|
|
| 15 |
+
| 0.2 | 511 / 3820 | 0.775 | 0.671 | 0.256 / 0.309 |
|
| 16 |
+
| 0.5 | 511 / 2256 | 0.776 | 0.638 | 0.357 / 0.427 |
|
| 17 |
+
| 1.2 | 511 / 688 | 0.738 | 0.577 | 0.713 / 0.533 |
|
| 18 |
+
|
| 19 |
+
## Decision rule on AMI test (511 complete / 3820 incomplete silences with a decision point; misses charged 3 s)
|
| 20 |
+
|
| 21 |
+
**Heads (this release)**
|
| 22 |
+
|
| 23 |
+
| rule | theta at 0.2 / 0.5 / 1.2 s | recall | FAR | p50 | p90 | mean latency | FAR by pause length <0.5 / 0.5-1.5 / >=1.5 s |
|
| 24 |
+
|---|---|---|---|---|---|---|---|
|
| 25 |
+
| one-shot at the VAD stop, theta 0.5 (stock rule) | 0.50 / - / - | 0.64 | 0.254 | 0.20 s | 3.00 s | 1.21 s | 0.19 / 0.24 / 0.46 |
|
| 26 |
+
| shipped table, 5% budget | 0.94 / 0.94 / 0.94 | 0.47 | 0.046 | 3.00 s | 3.00 s | 2.05 s | 0.00 / 0.03 / 0.21 |
|
| 27 |
+
| shipped table, 10% budget | 0.92 / 0.98 / 0.86 | 0.79 | 0.094 | 1.20 s | 3.00 s | 1.49 s | 0.01 / 0.04 / 0.50 |
|
| 28 |
+
| shipped table, 15% budget | 0.98 / 0.88 / 0.80 | 0.86 | 0.133 | 1.20 s | 3.00 s | 1.21 s | 0.00 / 0.09 / 0.61 |
|
| 29 |
+
| re-fitted on dev, 5% budget | 0.94 / 0.94 / 0.94 | 0.47 | 0.046 | 3.00 s | 3.00 s | 2.05 s | 0.00 / 0.03 / 0.21 |
|
| 30 |
+
| re-fitted on dev, 10% budget | 1.00 / 0.94 / 0.86 | 0.79 | 0.090 | 1.20 s | 3.00 s | 1.49 s | 0.00 / 0.04 / 0.50 |
|
| 31 |
+
| re-fitted on dev, 15% budget | 0.98 / 0.88 / 0.80 | 0.86 | 0.133 | 1.20 s | 3.00 s | 1.21 s | 0.00 / 0.09 / 0.61 |
|
| 32 |
+
|
| 33 |
+
**Frozen Smart Turn v3.2 (baseline, same protocol)**
|
| 34 |
+
|
| 35 |
+
| rule | theta at 0.2 / 0.5 / 1.2 s | recall | FAR | p50 | p90 | mean latency | FAR by pause length <0.5 / 0.5-1.5 / >=1.5 s |
|
| 36 |
+
|---|---|---|---|---|---|---|---|
|
| 37 |
+
| one-shot at the VAD stop, theta 0.5 (stock rule) | 0.50 / - / - | 0.51 | 0.303 | 0.20 s | 3.00 s | 1.56 s | 0.23 / 0.30 / 0.45 |
|
| 38 |
+
| re-fitted on dev, 5% budget | 1.00 / 1.00 / 0.96 | 0.37 | 0.056 | 3.00 s | 3.00 s | 2.34 s | 0.00 / 0.02 / 0.31 |
|
| 39 |
+
| re-fitted on dev, 10% budget | 1.00 / 1.00 / 0.26 | 0.71 | 0.106 | 1.20 s | 3.00 s | 1.72 s | 0.00 / 0.04 / 0.61 |
|
| 40 |
+
| re-fitted on dev, 15% budget | 1.00 / 1.00 / 0.02 | 0.87 | 0.137 | 1.20 s | 3.00 s | 1.44 s | 0.00 / 0.05 / 0.78 |
|
| 41 |
+
|
| 42 |
+
**No model**
|
| 43 |
+
|
| 44 |
+
| rule | theta at 0.2 / 0.5 / 1.2 s | recall | FAR | p50 | p90 | mean latency | FAR by pause length <0.5 / 0.5-1.5 / >=1.5 s |
|
| 45 |
+
|---|---|---|---|---|---|---|---|
|
| 46 |
+
| silence only, commit at 1.2 s | - / - / 0.00 | 1.00 | 0.180 | 1.20 s | 1.20 s | 1.20 s | 0.00 / 0.08 / 1.00 |
|
| 47 |
+
|
| 48 |
+
Scores cached in `./ami_eval_scores.npz`; audio from https://groups.inf.ed.ac.uk/ami/AMICorpusMirror/amicorpus (AMI Meeting Corpus, CC BY 4.0).
|
eval/ami_test.csv
ADDED
|
The diff for this file is too large to render.
See raw diff
|
|
|
rules/eager_tables.csv
ADDED
|
@@ -0,0 +1,9 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
commit,budget,theta_e,theta_c
|
| 2 |
+
far10,0.2,"(0.92, 0.84, 0.68)","(0.92, 0.98, 0.86)"
|
| 3 |
+
far10,0.3,"(0.92, 0.54, 0.2)","(0.92, 0.98, 0.86)"
|
| 4 |
+
far10,0.4,"(0.74, 0.24, 0.02)","(0.92, 0.98, 0.86)"
|
| 5 |
+
far10,0.5,"(0.42, 0.1, 0.02)","(0.92, 0.98, 0.86)"
|
| 6 |
+
far15,0.2,"(0.92, 0.84, 0.68)","(0.98, 0.88, 0.8)"
|
| 7 |
+
far15,0.3,"(0.84, 0.56, 0.42)","(0.98, 0.88, 0.8)"
|
| 8 |
+
far15,0.4,"(0.72, 0.24, 0.04)","(0.98, 0.88, 0.8)"
|
| 9 |
+
far15,0.5,"(0.42, 0.1, 0.02)","(0.98, 0.88, 0.8)"
|
rules/theta_tables.csv
ADDED
|
@@ -0,0 +1,7 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
model,far_budget,theta,test_recall,test_far,test_mean,test_p90,test_far_ge15
|
| 2 |
+
heads,0.05,"(0.94, 0.94, 0.94)",0.472,0.046,2.05,3.0,0.21
|
| 3 |
+
frozen_v32,0.05,"(1.0, 1.0, 0.96)",0.368,0.055,2.34,3.0,0.31
|
| 4 |
+
heads,0.1,"(0.92, 0.98, 0.86)",0.796,0.094,1.48,3.0,0.5
|
| 5 |
+
frozen_v32,0.1,"(1.0, 1.0, 0.28)",0.699,0.106,1.74,3.0,0.61
|
| 6 |
+
heads,0.15,"(0.98, 0.88, 0.8)",0.863,0.133,1.21,3.0,0.61
|
| 7 |
+
frozen_v32,0.15,"(1.0, 1.0, 0.02)",0.867,0.137,1.44,3.0,0.78
|
smart-turn-v3.2-encoder-pooled.onnx
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:37e2a4fe22e1c4efaeba4df40141e422a3b96519db9160ae9134962a936ba4ea
|
| 3 |
+
size 32411234
|