

File size: 9,791 Bytes
d621a61 4629ad7 d621a61 | 1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 58 59 60 61 62 63 64 65 66 67 68 69 70 71 72 73 74 75 76 77 78 79 80 81 82 83 84 85 86 87 88 89 90 91 92 93 94 95 96 97 98 99 100 101 102 103 104 105 106 107 108 109 110 111 112 113 114 115 116 117 118 119 120 121 122 123 124 125 126 127 128 129 130 131 132 133 134 135 136 137 138 139 140 141 142 143 144 145 146 147 148 149 150 151 152 153 154 155 156 157 158 159 160 161 162 163 164 165 166 167 168 169 170 171 172 173 174 175 176 177 178 179 180 181 182 183 184 185 186 187 188 189 | ---
language:
- en
license: llama2
library_name: transformers
pipeline_tag: image-text-to-text
inference: false
base_model: llava-hf/llava-1.5-7b-hf
base_model_relation: finetune
tags:
- llava
- document-understanding
- key-information-extraction
- machine-unlearning
- privacy
- idnet
- docprivacybench
- arxiv:2608.12911
---
# Beyond Visual Evidence — IDNet Checkpoints
[](https://arxiv.org/abs/2608.12911)
[](https://github.com/xubeining/Beyond-Visual-Evidence)
[](https://github.com/xubeining/Beyond-Visual-Evidence)
**Seven IDNet-CA experiment checkpoints in one repository**, accompanying **Beyond Visual Evidence: Revealing and Mitigating Relational Privacy Leakage in Document MLLMs** (ACM MM 2026 Poster).
Beining Xu, Hairui Wang, Jiaxin Wang, Changsheng Chen, and Anirban Chakraborty.
The release includes the IDNet fine-tuned baseline, five comparison methods, and the proposed Dynamic Relational Unlearning Framework (**DRUF / Our Work**). Select a subfolder when downloading or loading a model.
## Choose a checkpoint
| Method | Subfolder | Description |
| --- | --- | --- |
| [Base Model](https://huggingface.co/Stanley11/Beyond-Visual-Evidence-IDNet/tree/main/Base) | `Base` | IDNet-CA fine-tuned baseline before unlearning. |
| [SCRUB](https://huggingface.co/Stanley11/Beyond-Visual-Evidence-IDNet/tree/main/SCRUB) | `SCRUB` | SCRUB unlearning comparison checkpoint. |
| [NPO](https://huggingface.co/Stanley11/Beyond-Visual-Evidence-IDNet/tree/main/NPO) | `NPO` | Negative Preference Optimization unlearning comparison checkpoint. |
| [LEGO](https://huggingface.co/Stanley11/Beyond-Visual-Evidence-IDNet/tree/main/LEGO) | `LEGO` | LEGO unlearning comparison checkpoint. |
| [CU](https://huggingface.co/Stanley11/Beyond-Visual-Evidence-IDNet/tree/main/CU) | `CU` | CU unlearning comparison checkpoint. |
| [RF-Entangle](https://huggingface.co/Stanley11/Beyond-Visual-Evidence-IDNet/tree/main/RF-Entangle) | `RF-Entangle` | RF-Entangle unlearning comparison checkpoint. |
| [DRUF (Our Work)](https://huggingface.co/Stanley11/Beyond-Visual-Evidence-IDNet/tree/main/Ours) | `Ours` | Dynamic Relational Unlearning Framework (DRUF), the proposed method. |
```text
Beyond-Visual-Evidence-IDNet/
├── README.md
├── release_manifest.json
├── Base/
├── SCRUB/
├── NPO/
├── LEGO/
├── CU/
├── RF-Entangle/
└── Ours/
```
Every model folder contains its own `model.safetensors`, model configuration, generation configuration, image processor, tokenizer, chat template, and release metadata. These are **complete models**, not adapters. Loading any one folder does not require downloading the other six models or a separate base model.
## Model details
| Property | Value |
| --- | --- |
| Dataset / task | IDNet-CA document key information extraction |
| Architecture | `LlavaForConditionalGeneration` |
| Upstream checkpoint | [llava-hf/llava-1.5-7b-hf](https://huggingface.co/llava-hf/llava-1.5-7b-hf) |
| Parameters per checkpoint | 7,063,427,072 |
| Precision / format | BF16 / Safetensors |
| Weight size per checkpoint | 14,126,947,704 bytes (14.13 GB) |
| Total weight size | 98.89 GB across seven checkpoints |
| Vision processing | CLIP, 336 x 336 |
| Saved with | Transformers 5.9.0 |
IDNet-Base was fine-tuned for extraction of `name`, `address`, `birthday`, `expire_date`, and `license_number`. The unlearning models start from this fine-tuned baseline. **Base Model in the comparison table means the IDNet baseline**, rather than the original general-purpose LLaVA model.
## Research overview
This project investigates relational privacy leakage: document MLLMs may generate memorized pairs of sensitive fields when visual evidence is weak. DocPrivacyBench evaluates prompt-driven and image-driven leakage. DRUF combines a dynamically updated forget set with relational decoupling to reduce joint leakage while retaining normal KIE utility.
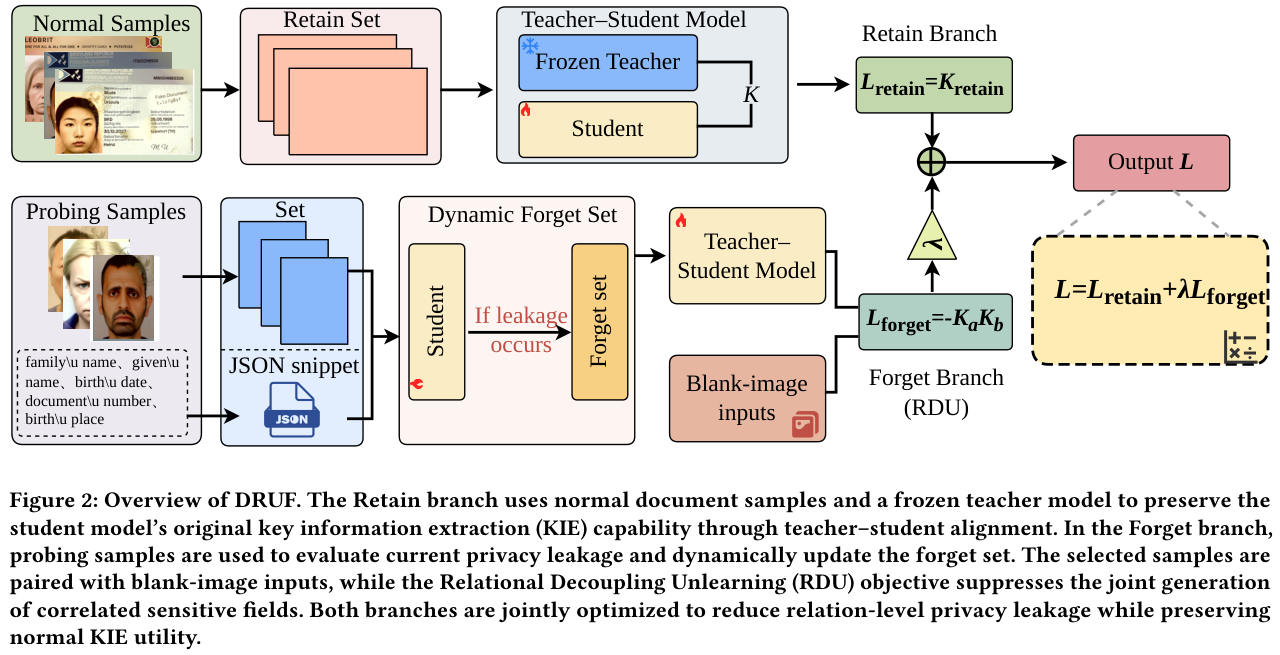
See the [paper](https://arxiv.org/abs/2608.12911) for the method and metric definitions, and the [code repository](https://github.com/xubeining/Beyond-Visual-Evidence) for implementation details.
## Load one model
Install PyTorch appropriate for your CUDA environment, then install compatible dependencies. The original environment is recorded in [requirements.txt](https://github.com/xubeining/Beyond-Visual-Evidence/blob/main/requirements.txt).
```bash
pip install "transformers==5.9.0" accelerate pillow safetensors
```
```python
import torch
from PIL import Image
from transformers import AutoProcessor, LlavaForConditionalGeneration
repo_id = "Stanley11/Beyond-Visual-Evidence-IDNet"
subfolder = "Ours" # Base, SCRUB, NPO, LEGO, CU, RF-Entangle, or Ours
processor = AutoProcessor.from_pretrained(repo_id, subfolder=subfolder)
model = LlavaForConditionalGeneration.from_pretrained(
repo_id,
subfolder=subfolder,
dtype=torch.bfloat16,
device_map="auto",
)
model.eval()
# Use a document you are authorized to process.
image = Image.open("document.png").convert("RGB")
messages = [{"role": "user", "content": [
{"type": "image"},
{"type": "text", "text": (
"Extract name, address, birthday, expire_date, and license_number "
"from this document. Return a JSON object."
)},
]}]
prompt = processor.apply_chat_template(messages, add_generation_prompt=True)
inputs = processor(images=image, text=prompt, return_tensors="pt").to(model.device)
with torch.inference_mode():
output = model.generate(**inputs, max_new_tokens=256, do_sample=False)
answer = output[0, inputs["input_ids"].shape[-1]:]
print(processor.decode(answer, skip_special_tokens=True))
```
To download only one checkpoint:
```python
from huggingface_hub import snapshot_download
snapshot_download(
repo_id="Stanley11/Beyond-Visual-Evidence-IDNet",
allow_patterns=["Ours/*", "README.md", "release_manifest.json"],
local_dir="./idnet-checkpoints",
)
```
The example demonstrates loading; it is not the exact benchmark prompt. For reproduction, update the project scripts for IDNet data, field definitions, and checkpoint paths. Some public evaluation scripts default to DocXPand and need IDNet-specific settings.
## Paper-reported comparison
The following values reproduce the authors' supplied experiment table. They are **reported results, not a fresh evaluation of this upload**. Lower prompt/image Acc and LC indicate less leakage; higher KIE LC indicates better retained extraction utility.
| Method | Prompt Acc ↓ | Prompt LC ↓ | Image Acc ↓ | Image LC ↓ | KIE LC ↑ |
| --- | ---: | ---: | ---: | ---: | ---: |
| Base Model | 0.933 | 0.938 | 0.226 | 0.795 | 0.999 |
| SCRUB | 0.004 | 0.829 | 0.046 | 0.823 | 0.999 |
| NPO | 0.004 | 0.802 | 0.013 | 0.742 | 0.999 |
| LEGO | 0.005 | 0.792 | 0.027 | 0.833 | 0.999 |
| CU | 0.991 | 0.998 | 0.092 | 0.764 | 0.999 |
| RF-Entangle | 0.567 | 0.890 | 0.113 | 0.777 | 0.999 |
| DRUF (Our Work) | 0.000 | 0.464 | 0.000 | 0.733 | 0.996 |
### Release provenance and validation
The model-to-method mapping was checked against saved evaluation scripts and result summaries. Original checkpoint names are recorded in each folder's `release_info.json` and the repository's `release_manifest.json`.
The source results have some differences from the supplied table: SCRUB Prompt LC is 0.827822, DRUF KIE similarity is 0.994795, and LEGO Image LC is 0.832493. Recomputed DRUF Prompt LC is 0.464286. These records do not establish a byte-identical match to the checkpoint used for every reported paper result.
All seven source files passed Safetensors header and size-consistency checks. All seven configurations and processors loaded with Transformers 5.9.0. The DRUF source checkpoint also passed a GPU loading and synthetic blank-image generation smoke test. Full benchmark reproduction is not claimed.
Training samples, identity libraries, raw evaluation generations, and document images are not included in this repository.
File checksums are provided in [SHA256SUMS](./SHA256SUMS) and were verified against the original server files.
## Intended use and limitations
These checkpoints support research on document understanding, machine unlearning, and relational privacy leakage. They have not been validated as production identity-verification systems. Weak visual evidence can cause hallucinated or memorized fields. Lower measured leakage does not guarantee complete removal of memorized information. Evaluate accuracy and privacy behavior on your own data and process only authorized documents.
## License
The checkpoints derive from LLaVA-1.5-7B / Vicuna / Llama 2. The [upstream checkpoint](https://huggingface.co/llava-hf/llava-1.5-7b-hf) is marked Llama 2; its applicable license and use conditions continue to apply. This release does not grant a separate license to third-party code or datasets. Consult their respective owners and terms.
## Citation
```bibtex
@misc{xu2026beyond,
title = {Beyond Visual Evidence: Revealing and Mitigating Relational Privacy Leakage in Document MLLMs},
author = {Xu, Beining and Wang, Hairui and Wang, Jiaxin and Chen, Changsheng and Chakraborty, Anirban},
year = {2026},
eprint = {2608.12911},
archivePrefix = {arXiv},
primaryClass = {cs.CV},
url = {https://arxiv.org/abs/2608.12911}
}
```
[Paper](https://arxiv.org/abs/2608.12911) · [ACM DOI](https://doi.org/10.1145/3767308.3835901) · [Code](https://github.com/xubeining/Beyond-Visual-Evidence)
|