


Upload folder using huggingface_hub
Browse files- README.md +234 -109
- __init__.py +5 -4
- configuration_esmfold2.py +313 -283
- esmfold2_affine3d.py +0 -1
- esmfold2_aligner.py +0 -1
- esmfold2_atom_indexer.py +0 -1
- esmfold2_conformers.py +0 -1
- esmfold2_constants.py +0 -1
- esmfold2_constants_esm3.py +0 -1
- esmfold2_input_builder.py +0 -1
- esmfold2_metrics.py +1 -2
- esmfold2_misc.py +0 -1
- esmfold2_mmcif_parsing.py +1 -2
- esmfold2_molecular_complex.py +2 -2
- esmfold2_msa.py +0 -1
- esmfold2_msa_filter_sequences.py +0 -1
- esmfold2_normalize_coordinates.py +0 -1
- esmfold2_output.py +0 -1
- esmfold2_paired_msa.py +0 -1
- esmfold2_parsing.py +0 -1
- esmfold2_predicted_aligned_error.py +0 -1
- esmfold2_prepare_input.py +0 -1
- esmfold2_processor.py +0 -1
- esmfold2_protein_chain.py +1 -2
- esmfold2_protein_complex.py +1 -2
- esmfold2_protein_structure.py +1 -2
- esmfold2_residue_constants.py +0 -1
- esmfold2_sequential_dataclass.py +0 -1
- esmfold2_system.py +0 -1
- esmfold2_types.py +0 -1
- esmfold2_utils_types.py +0 -1
- modeling_esmfold2.py +0 -0
- modeling_esmfold2_common.py +0 -0
- modeling_esmfold2_experimental.py +1001 -0
- protein_utils.py +488 -488
README.md
CHANGED
|
@@ -1,122 +1,247 @@
|
|
| 1 |
-
---
|
| 2 |
-
library_name: transformers
|
| 3 |
-
tags:
|
| 4 |
-
- biology
|
| 5 |
-
- protein-structure
|
| 6 |
-
- esmfold2
|
| 7 |
-
- multimodal-protein-model
|
| 8 |
-
---
|
| 9 |
-
|
| 10 |
-
# FastPLMs ESMFold2
|
| 11 |
-
|
| 12 |
-
FastPLMs ESMFold2 is a self-contained Hugging Face `AutoModel` wrapper for
|
| 13 |
-
|
| 14 |
-
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
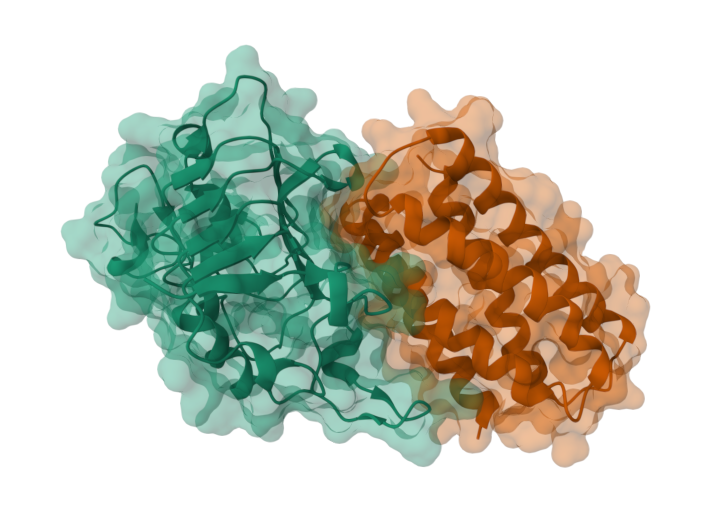
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 15 |
|
| 16 |
```python
|
| 17 |
-
import torch
|
| 18 |
-
from transformers import AutoModel
|
| 19 |
-
|
| 20 |
model = AutoModel.from_pretrained(
|
| 21 |
"Synthyra/ESMFold2-Fast",
|
| 22 |
-
trust_remote_code=True,
|
| 23 |
-
|
| 24 |
-
).
|
| 25 |
-
```
|
| 26 |
-
|
| 27 |
-
Use `Synthyra/ESMFold2` for the full model and `Synthyra/ESMFold2-Fast` for the faster release variant.
|
| 28 |
-
The folding trunk runs in fp32; the 6B ESMC backbone is loaded in bf16 by default via `esmc_precision="bf16"`.
|
| 29 |
-
|
| 30 |
-
## Fold One Protein
|
| 31 |
-
|
| 32 |
-
```python
|
| 33 |
-
sequence = "MKTLLILAVVAAALA"
|
| 34 |
-
|
| 35 |
-
result = model.fold_protein(
|
| 36 |
-
sequence,
|
| 37 |
-
num_loops=3,
|
| 38 |
-
num_sampling_steps=50,
|
| 39 |
-
num_diffusion_samples=1,
|
| 40 |
-
seed=0,
|
| 41 |
-
)
|
| 42 |
-
|
| 43 |
-
print(float(result.plddt.mean()))
|
| 44 |
-
print(float(result.ptm))
|
| 45 |
-
```
|
| 46 |
-
|
| 47 |
-
## Save mmCIF or PDB
|
| 48 |
-
|
| 49 |
-
```python
|
| 50 |
-
model.save_as_cif(result, "prediction.cif")
|
| 51 |
-
model.save_as_pdb(result, "prediction.pdb")
|
| 52 |
-
|
| 53 |
-
cif_text = model.result_to_cif(result)
|
| 54 |
-
pdb_text = model.result_to_pdb(result)
|
| 55 |
-
```
|
| 56 |
-
|
| 57 |
-
`result_to_cif` preserves the full `MolecularComplex`. `result_to_pdb` converts through Biohub's protein-only `ProteinComplex` representation, so use mmCIF for complexes with ligands or nucleic acids.
|
| 58 |
-
|
| 59 |
-
## Fold Complexes
|
| 60 |
-
|
| 61 |
-
```python
|
| 62 |
-
types = model.input_types
|
| 63 |
-
|
| 64 |
-
complex_input = types.StructurePredictionInput(
|
| 65 |
-
sequences=[
|
| 66 |
-
types.ProteinInput(id="A", sequence="MKTLLILAVVAAALA"),
|
| 67 |
-
types.DNAInput(id="B", sequence="GATAGC"),
|
| 68 |
-
types.LigandInput(id="L", ccd=["SAH"]),
|
| 69 |
-
]
|
| 70 |
-
)
|
| 71 |
-
|
| 72 |
-
result = model.fold(
|
| 73 |
-
complex_input,
|
| 74 |
-
num_loops=3,
|
| 75 |
-
num_sampling_steps=50,
|
| 76 |
-
num_diffusion_samples=1,
|
| 77 |
-
seed=0,
|
| 78 |
-
)
|
| 79 |
-
|
| 80 |
-
model.save_as_cif(result, "complex_prediction.cif")
|
| 81 |
-
```
|
| 82 |
-
|
| 83 |
-
## Use MSAs
|
| 84 |
-
|
| 85 |
-
```python
|
| 86 |
-
types = model.input_types
|
| 87 |
-
|
| 88 |
-
msa = types.MSA.from_a3m("query.a3m", max_sequences=128)
|
| 89 |
-
input_with_msa = types.StructurePredictionInput(
|
| 90 |
-
sequences=[
|
| 91 |
-
types.ProteinInput(id="A", sequence=msa.query, msa=msa),
|
| 92 |
-
]
|
| 93 |
-
)
|
| 94 |
-
|
| 95 |
-
result = model.fold(input_with_msa, num_sampling_steps=50, seed=0)
|
| 96 |
-
```
|
| 97 |
-
|
| 98 |
-
## Raw Tensor Inference
|
| 99 |
-
|
| 100 |
-
```python
|
| 101 |
-
features, chain_infos = model.prepare_structure_input(complex_input, seed=0)
|
| 102 |
-
|
| 103 |
-
with torch.inference_mode():
|
| 104 |
-
output = model(
|
| 105 |
-
**features,
|
| 106 |
-
num_loops=3,
|
| 107 |
-
num_sampling_steps=50,
|
| 108 |
-
num_diffusion_samples=1,
|
| 109 |
-
)
|
| 110 |
-
|
| 111 |
-
decoded = model.input_builder.decode(output, features, chain_infos)
|
| 112 |
```
|
| 113 |
|
| 114 |
-
|
|
|
|
|
|
|
| 115 |
|
| 116 |
```python
|
| 117 |
model = AutoModel.from_pretrained(
|
| 118 |
"Synthyra/ESMFold2-Fast",
|
| 119 |
trust_remote_code=True,
|
| 120 |
-
|
| 121 |
).cuda().eval()
|
| 122 |
```
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
---
|
| 2 |
+
library_name: transformers
|
| 3 |
+
tags:
|
| 4 |
+
- biology
|
| 5 |
+
- protein-structure
|
| 6 |
+
- esmfold2
|
| 7 |
+
- multimodal-protein-model
|
| 8 |
+
---
|
| 9 |
+
|
| 10 |
+
# FastPLMs ESMFold2
|
| 11 |
+
|
| 12 |
+
FastPLMs ESMFold2 is a self-contained Hugging Face `AutoModel` wrapper for
|
| 13 |
+
Biohub's ESMFold2, ESMFold2-Fast, and experimental ESMFold2 structure
|
| 14 |
+
predictors. It vendors the released Biohub ESMFold2 model code, input builder,
|
| 15 |
+
MSA helpers, and structure export utilities, while loading the PLM backbone
|
| 16 |
+
through FastPLMs ESM++.
|
| 17 |
+
|
| 18 |
+
## Load With AutoModel
|
| 19 |
+
|
| 20 |
+
```python
|
| 21 |
+
import torch
|
| 22 |
+
from transformers import AutoModel
|
| 23 |
+
|
| 24 |
+
model = AutoModel.from_pretrained(
|
| 25 |
+
"Synthyra/ESMFold2-Fast",
|
| 26 |
+
trust_remote_code=True,
|
| 27 |
+
dtype=torch.float32,
|
| 28 |
+
).eval().cuda()
|
| 29 |
+
```
|
| 30 |
+
|
| 31 |
+
Use `Synthyra/ESMFold2` for the full model, `Synthyra/ESMFold2-Fast` for the
|
| 32 |
+
faster release variant, and the `Synthyra/ESMFold2-Experimental*` checkpoints
|
| 33 |
+
for differentiable binder design and experimental critic ensembles.
|
| 34 |
+
The folding trunk runs in fp32; the 6B FastPLMs ESM++ backbone is loaded in
|
| 35 |
+
bf16 by default via `esmc_precision="bf16"` and uses the flex attention backend
|
| 36 |
+
by default inside ESMFold2.
|
| 37 |
+
|
| 38 |
+
## Fold One Protein
|
| 39 |
+
|
| 40 |
+
```python
|
| 41 |
+
sequence = "MKTLLILAVVAAALA"
|
| 42 |
+
|
| 43 |
+
result = model.fold_protein(
|
| 44 |
+
sequence,
|
| 45 |
+
num_loops=3,
|
| 46 |
+
num_sampling_steps=50,
|
| 47 |
+
num_diffusion_samples=1,
|
| 48 |
+
seed=0,
|
| 49 |
+
)
|
| 50 |
+
|
| 51 |
+
print(float(result.plddt.mean()))
|
| 52 |
+
print(float(result.ptm))
|
| 53 |
+
```
|
| 54 |
+
|
| 55 |
+
## Experimental Test-Time Training
|
| 56 |
+
|
| 57 |
+
TTT is disabled by default. Standard `fold_protein(...)`, `fold(...)`, raw tensor
|
| 58 |
+
inference, and `state_dict()` keys are unchanged unless you explicitly pass
|
| 59 |
+
`ttt=True` or call `fold_protein_ttt(...)`.
|
| 60 |
+
|
| 61 |
+
The ESMFold2 TTT path is experimental and protein-only in v1. It trains local
|
| 62 |
+
LoRA adapters only on `_esmc` with a masked language modeling objective. The
|
| 63 |
+
folding trunk, confidence head, diffusion head, and structure input pipeline are
|
| 64 |
+
frozen. TTT can improve difficult low-confidence folds, but it adds substantial
|
| 65 |
+
test-time compute and can degrade already confident predictions.
|
| 66 |
+
|
| 67 |
+
```python
|
| 68 |
+
result = model.fold_protein(
|
| 69 |
+
"MSTNPKPQRKTKRNT",
|
| 70 |
+
num_loops=1,
|
| 71 |
+
num_sampling_steps=10,
|
| 72 |
+
num_diffusion_samples=1,
|
| 73 |
+
seed=0,
|
| 74 |
+
ttt=True,
|
| 75 |
+
ttt_config={
|
| 76 |
+
"steps": 1,
|
| 77 |
+
"ags": 1,
|
| 78 |
+
"batch_size": 1,
|
| 79 |
+
"lora_rank": 8,
|
| 80 |
+
"lora_alpha": 32.0,
|
| 81 |
+
},
|
| 82 |
+
)
|
| 83 |
+
|
| 84 |
+
print(result.ttt_metrics["losses"])
|
| 85 |
+
print(result.ttt_metrics["step_plddts"])
|
| 86 |
+
print(result.ttt_metrics["best_step"])
|
| 87 |
+
```
|
| 88 |
+
|
| 89 |
+
`load_esmc=True` is required for TTT because the ESM++ MLM head is loaded lazily
|
| 90 |
+
from `config.esmc_id`. If that pretrained MLM head cannot be loaded, TTT raises
|
| 91 |
+
an assertion instead of silently using a random head.
|
| 92 |
+
|
| 93 |
+
## Save mmCIF or PDB
|
| 94 |
+
|
| 95 |
+
```python
|
| 96 |
+
model.save_as_cif(result, "prediction.cif")
|
| 97 |
+
model.save_as_pdb(result, "prediction.pdb")
|
| 98 |
+
|
| 99 |
+
cif_text = model.result_to_cif(result)
|
| 100 |
+
pdb_text = model.result_to_pdb(result)
|
| 101 |
+
```
|
| 102 |
+
|
| 103 |
+
`result_to_cif` preserves the full `MolecularComplex`. `result_to_pdb` converts through Biohub's protein-only `ProteinComplex` representation, so use mmCIF for complexes with ligands or nucleic acids.
|
| 104 |
+
|
| 105 |
+
## Fold Complexes
|
| 106 |
+
|
| 107 |
+
```python
|
| 108 |
+
types = model.input_types
|
| 109 |
+
|
| 110 |
+
complex_input = types.StructurePredictionInput(
|
| 111 |
+
sequences=[
|
| 112 |
+
types.ProteinInput(id="A", sequence="MKTLLILAVVAAALA"),
|
| 113 |
+
types.DNAInput(id="B", sequence="GATAGC"),
|
| 114 |
+
types.LigandInput(id="L", ccd=["SAH"]),
|
| 115 |
+
]
|
| 116 |
+
)
|
| 117 |
+
|
| 118 |
+
result = model.fold(
|
| 119 |
+
complex_input,
|
| 120 |
+
num_loops=3,
|
| 121 |
+
num_sampling_steps=50,
|
| 122 |
+
num_diffusion_samples=1,
|
| 123 |
+
seed=0,
|
| 124 |
+
)
|
| 125 |
+
|
| 126 |
+
model.save_as_cif(result, "complex_prediction.cif")
|
| 127 |
+
```
|
| 128 |
+
|
| 129 |
+
## Binder Design With FastPLMs ESMFold2
|
| 130 |
+
|
| 131 |
+
FastPLMs includes a FastPLMs-only port of the Biohub ESMFold2 binder design
|
| 132 |
+
tutorial at `cookbook/tutorials/binder_design_fastplms.py`. The workflow uses
|
| 133 |
+
ESMFold2 experimental checkpoints for differentiable folding losses, ESM++ for
|
| 134 |
+
sequence regularization, and ESMFold2 hero critics for final confidence scoring.
|
| 135 |
+
|
| 136 |
+
|
| 137 |
+
|
| 138 |
+
The optimizer follows the official strategy:
|
| 139 |
+
|
| 140 |
+
1. Optimize mutable `#` residues as continuous amino acid logits.
|
| 141 |
+
2. Suppress cysteine design by masking cysteine logits and gradients.
|
| 142 |
+
3. Backpropagate through ESMFold2 `res_type_soft` using intra-contact,
|
| 143 |
+
inter-contact, and globularity losses from the distogram.
|
| 144 |
+
4. Add an ESM++ masked-LM pseudoperplexity regularizer on mutable binder
|
| 145 |
+
residues.
|
| 146 |
+
5. Keep the late-trajectory sequence with the best iPTM.
|
| 147 |
+
6. Fold the selected sequence with the final critic ensemble and write
|
| 148 |
+
`results.parquet`, `selection.parquet`, `trajectory.jsonl`,
|
| 149 |
+
`best_sequences.fasta`, and per-critic PDB/CIF/logit files.
|
| 150 |
+
|
| 151 |
+
Run the verified EGFR 128 amino acid de novo minibinder example:
|
| 152 |
+
|
| 153 |
+
```bash
|
| 154 |
+
cd /home/ubuntu/FastPLMs
|
| 155 |
+
|
| 156 |
+
sudo -n docker run --gpus all --rm \
|
| 157 |
+
-v /home/ubuntu/FastPLMs:/app \
|
| 158 |
+
-v /home/ubuntu/FastPLMs:/workspace \
|
| 159 |
+
-v /home/ubuntu/.cache/huggingface:/workspace/.cache/huggingface \
|
| 160 |
+
-w /workspace fastplms-esmfold2 \
|
| 161 |
+
python /app/cookbook/tutorials/binder_design_fastplms.py \
|
| 162 |
+
--backend local \
|
| 163 |
+
--target-name egfr \
|
| 164 |
+
--binder-sequence '################################################################################################################################' \
|
| 165 |
+
--not-antibody \
|
| 166 |
+
--steps 150 \
|
| 167 |
+
--batch-size 1 \
|
| 168 |
+
--seed 103 \
|
| 169 |
+
--output-dir /workspace/campaign_egfr_len128_b1_s150_seed103_consensus_cli
|
| 170 |
+
```
|
| 171 |
+
|
| 172 |
+
Verified result:
|
| 173 |
+
|
| 174 |
+
| Metric | Value |
|
| 175 |
+
| :--- | :--- |
|
| 176 |
+
| Binder length | `128` |
|
| 177 |
+
| Seed | `103` |
|
| 178 |
+
| Steps | `150` |
|
| 179 |
+
| Hero mean iPTM | `0.913870` |
|
| 180 |
+
| Hero min iPTM | `0.904600` |
|
| 181 |
+
| All four hero critics above 0.9 | `True` |
|
| 182 |
+
|
| 183 |
+
Binder sequence:
|
| 184 |
+
|
| 185 |
+
```text
|
| 186 |
+
SAVKHLLEIVKYLEEAIEKALEVDPVFLVPPAAEELLIAAKVIKELAKENPELIEVYELLMKAVKGLKKLVRSNDKEILREVIRLLRKAAKVIREILKNNPDLDPELRKALEELAKVLEEIAEVLEQQ
|
| 187 |
+
```
|
| 188 |
+
|
| 189 |
+
See the full guide in [`docs/binder_design.md`](https://github.com/Synthyra/FastPLMs/blob/main/docs/binder_design.md)
|
| 190 |
+
for Modal execution, official pI and selection scoring, per-critic metrics, and
|
| 191 |
+
the tested cheaper step-count boundary.
|
| 192 |
+
|
| 193 |
+
## Use MSAs
|
| 194 |
+
|
| 195 |
+
```python
|
| 196 |
+
types = model.input_types
|
| 197 |
+
|
| 198 |
+
msa = types.MSA.from_a3m("query.a3m", max_sequences=128)
|
| 199 |
+
input_with_msa = types.StructurePredictionInput(
|
| 200 |
+
sequences=[
|
| 201 |
+
types.ProteinInput(id="A", sequence=msa.query, msa=msa),
|
| 202 |
+
]
|
| 203 |
+
)
|
| 204 |
+
|
| 205 |
+
result = model.fold(input_with_msa, num_sampling_steps=50, seed=0)
|
| 206 |
+
```
|
| 207 |
+
|
| 208 |
+
## Raw Tensor Inference
|
| 209 |
+
|
| 210 |
+
```python
|
| 211 |
+
features, chain_infos = model.prepare_structure_input(complex_input, seed=0)
|
| 212 |
+
|
| 213 |
+
with torch.inference_mode():
|
| 214 |
+
output = model(
|
| 215 |
+
**features,
|
| 216 |
+
num_loops=3,
|
| 217 |
+
num_sampling_steps=50,
|
| 218 |
+
num_diffusion_samples=1,
|
| 219 |
+
)
|
| 220 |
+
|
| 221 |
+
decoded = model.input_builder.decode(output, features, chain_infos)
|
| 222 |
+
```
|
| 223 |
+
|
| 224 |
+
Set `load_esmc=False` when loading if you want to provide precomputed `lm_hidden_states` manually or run folding-trunk tests without loading the 6B ESM++ backbone:
|
| 225 |
|
| 226 |
```python
|
|
|
|
|
|
|
|
|
|
| 227 |
model = AutoModel.from_pretrained(
|
| 228 |
"Synthyra/ESMFold2-Fast",
|
| 229 |
+
trust_remote_code=True,
|
| 230 |
+
load_esmc=False,
|
| 231 |
+
).cuda().eval()
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 232 |
```
|
| 233 |
|
| 234 |
+
For FP8 LM inference, install `transformer_engine.pytorch` in a CUDA
|
| 235 |
+
environment with FP8-capable hardware and load the shared FastPLMs ESM++
|
| 236 |
+
backbone with:
|
| 237 |
|
| 238 |
```python
|
| 239 |
model = AutoModel.from_pretrained(
|
| 240 |
"Synthyra/ESMFold2-Fast",
|
| 241 |
trust_remote_code=True,
|
| 242 |
+
esmc_precision="fp8",
|
| 243 |
).cuda().eval()
|
| 244 |
```
|
| 245 |
+
|
| 246 |
+
FP8 is inference-only for the ESMFold2 LM backbone. TTT remains a bf16/fp32
|
| 247 |
+
path.
|
__init__.py
CHANGED
|
@@ -1,4 +1,5 @@
|
|
| 1 |
-
from .configuration_esmfold2 import ESMFold2Config
|
| 2 |
-
from .
|
| 3 |
-
|
| 4 |
-
|
|
|
|
|
|
| 1 |
+
from .configuration_esmfold2 import ESMFold2Config
|
| 2 |
+
from .modeling_esmfold2_experimental import ESMFold2ExperimentalModel
|
| 3 |
+
from .modeling_esmfold2 import ESMFold2Model
|
| 4 |
+
|
| 5 |
+
__all__ = ["ESMFold2Config", "ESMFold2ExperimentalModel", "ESMFold2Model"]
|
configuration_esmfold2.py
CHANGED
|
@@ -1,194 +1,206 @@
|
|
| 1 |
-
# Copyright 2026 Biohub. All rights reserved.
|
| 2 |
-
#
|
| 3 |
-
# Licensed under the Apache License, Version 2.0 (the "License");
|
| 4 |
-
# you may not use this file except in compliance with the License.
|
| 5 |
-
# You may obtain a copy of the License at
|
| 6 |
-
#
|
| 7 |
-
# http://www.apache.org/licenses/LICENSE-2.0
|
| 8 |
-
#
|
| 9 |
-
# Unless required by applicable law or agreed to in writing, software
|
| 10 |
-
# distributed under the License is distributed on an "AS IS" BASIS,
|
| 11 |
-
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
| 12 |
-
# See the License for the specific language governing permissions and
|
| 13 |
-
# limitations under the License.
|
| 14 |
-
"""ESMFold2 model configuration."""
|
| 15 |
-
|
| 16 |
-
from __future__ import annotations
|
| 17 |
-
|
| 18 |
-
from dataclasses import asdict, dataclass, field
|
| 19 |
-
|
| 20 |
-
from transformers.configuration_utils import PretrainedConfig
|
| 21 |
-
|
| 22 |
-
# ---------------------------------------------------------------------------
|
| 23 |
-
# Nested dataclass configs
|
| 24 |
-
# ---------------------------------------------------------------------------
|
| 25 |
-
|
| 26 |
-
_DEFAULT_ESMC_HF_REPO = "
|
| 27 |
-
|
| 28 |
-
|
| 29 |
-
|
| 30 |
-
|
| 31 |
-
""
|
| 32 |
-
|
| 33 |
-
|
| 34 |
-
|
| 35 |
-
|
| 36 |
-
|
| 37 |
-
|
| 38 |
-
|
| 39 |
-
|
| 40 |
-
|
| 41 |
-
@dataclass
|
| 42 |
-
class
|
| 43 |
-
"""
|
| 44 |
-
|
| 45 |
-
enabled: bool =
|
| 46 |
-
|
| 47 |
-
|
| 48 |
-
|
| 49 |
-
|
| 50 |
-
|
| 51 |
-
|
| 52 |
-
|
| 53 |
-
|
| 54 |
-
|
| 55 |
-
|
| 56 |
-
|
| 57 |
-
|
| 58 |
-
|
| 59 |
-
|
| 60 |
-
|
| 61 |
-
|
| 62 |
-
|
| 63 |
-
|
| 64 |
-
|
| 65 |
-
|
| 66 |
-
|
| 67 |
-
|
| 68 |
-
|
| 69 |
-
|
| 70 |
-
|
| 71 |
-
|
| 72 |
-
|
| 73 |
-
|
| 74 |
-
|
| 75 |
-
|
| 76 |
-
|
| 77 |
-
|
| 78 |
-
|
| 79 |
-
|
| 80 |
-
|
| 81 |
-
|
| 82 |
-
|
| 83 |
-
|
| 84 |
-
|
| 85 |
-
|
| 86 |
-
|
| 87 |
-
|
| 88 |
-
|
| 89 |
-
|
| 90 |
-
|
| 91 |
-
|
| 92 |
-
|
| 93 |
-
|
| 94 |
-
|
| 95 |
-
|
| 96 |
-
|
| 97 |
-
|
| 98 |
-
|
| 99 |
-
|
| 100 |
-
|
| 101 |
-
|
| 102 |
-
|
| 103 |
-
|
| 104 |
-
|
| 105 |
-
|
| 106 |
-
|
| 107 |
-
|
| 108 |
-
|
| 109 |
-
|
| 110 |
-
|
| 111 |
-
|
| 112 |
-
|
| 113 |
-
|
| 114 |
-
|
| 115 |
-
|
| 116 |
-
|
| 117 |
-
|
| 118 |
-
|
| 119 |
-
|
| 120 |
-
|
| 121 |
-
|
| 122 |
-
|
| 123 |
-
|
| 124 |
-
|
| 125 |
-
|
| 126 |
-
|
| 127 |
-
|
| 128 |
-
|
| 129 |
-
|
| 130 |
-
|
| 131 |
-
|
| 132 |
-
|
| 133 |
-
|
| 134 |
-
|
| 135 |
-
|
| 136 |
-
|
| 137 |
-
|
| 138 |
-
|
| 139 |
-
|
| 140 |
-
|
| 141 |
-
|
| 142 |
-
|
| 143 |
-
|
| 144 |
-
|
| 145 |
-
|
| 146 |
-
|
| 147 |
-
|
| 148 |
-
|
| 149 |
-
|
| 150 |
-
|
| 151 |
-
|
| 152 |
-
|
| 153 |
-
|
| 154 |
-
|
| 155 |
-
|
| 156 |
-
|
| 157 |
-
|
| 158 |
-
|
| 159 |
-
|
| 160 |
-
|
| 161 |
-
|
| 162 |
-
|
| 163 |
-
|
| 164 |
-
|
| 165 |
-
|
| 166 |
-
|
| 167 |
-
|
| 168 |
-
|
| 169 |
-
|
| 170 |
-
|
| 171 |
-
|
| 172 |
-
|
| 173 |
-
|
| 174 |
-
|
| 175 |
-
|
| 176 |
-
|
| 177 |
-
|
| 178 |
-
|
| 179 |
-
|
| 180 |
-
|
| 181 |
-
|
| 182 |
-
|
| 183 |
-
|
| 184 |
-
|
| 185 |
-
|
| 186 |
-
|
| 187 |
-
|
| 188 |
-
|
| 189 |
-
|
| 190 |
-
|
| 191 |
-
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 192 |
lm_dropout (`float`, defaults to 0.0):
|
| 193 |
Dropout probability on LM pair embeddings. When > 0, dropout is
|
| 194 |
applied with ``training=True`` (including at inference) to match
|
|
@@ -196,103 +208,121 @@ class ESMFold2Config(PretrainedConfig):
|
|
| 196 |
force_lm_dropout_during_inference (`bool`, defaults to False):
|
| 197 |
When True, apply ``lm_dropout`` even when ``model.eval()`` and
|
| 198 |
``lm_dropout`` > 0. Binder-design loads set this to True.
|
|
|
|
|
|
|
|
|
|
| 199 |
disable_msa_features (`bool`, defaults to False):
|
| 200 |
When True, zero out MSA-derived ``profile`` and ``deletion_mean``
|
| 201 |
before the inputs embedder (experimental medium/large checkpoints).
|
| 202 |
-
inputs (`InputsEmbedderConfig`):
|
| 203 |
-
Configuration for the inputs embedder module.
|
| 204 |
-
folding_trunk (`FoldingTrunkConfig`):
|
| 205 |
-
Configuration for the folding trunk.
|
| 206 |
-
structure_head (`DiffusionStructureHeadConfig`):
|
| 207 |
-
Configuration for the diffusion-based structure prediction head.
|
| 208 |
-
confidence_head (`ConfidenceHeadConfig`):
|
| 209 |
-
Configuration for the confidence prediction head.
|
| 210 |
-
|
| 211 |
-
Examples:
|
| 212 |
-
|
| 213 |
-
```python
|
| 214 |
-
>>> from transformers import ESMFold2Config, ESMFold2ExperimentalModel
|
| 215 |
-
|
| 216 |
-
>>> # Initializing an ESMFold2 configuration
|
| 217 |
-
>>> configuration = ESMFold2Config(type="experimental")
|
| 218 |
-
|
| 219 |
-
>>> # Initializing a model (with random weights) from the configuration
|
| 220 |
-
>>> model = ESMFold2ExperimentalModel(configuration)
|
| 221 |
-
|
| 222 |
-
>>> # Accessing the model configuration
|
| 223 |
-
>>> configuration = model.config
|
| 224 |
-
```
|
| 225 |
-
"""
|
| 226 |
-
|
| 227 |
-
model_type = "esmfold2"
|
| 228 |
-
has_no_defaults_at_init = True
|
| 229 |
-
|
| 230 |
-
def __init__(self, **kwargs):
|
| 231 |
-
super().__init__(**kwargs)
|
| 232 |
-
|
| 233 |
-
self.type: str = kwargs.get("type", "release")
|
| 234 |
-
if self.type not in ("release", "experimental"):
|
| 235 |
-
raise ValueError(
|
| 236 |
-
f"ESMFold2Config.type must be 'release' or 'experimental', "
|
| 237 |
-
f"got {self.type!r}"
|
| 238 |
-
)
|
| 239 |
-
|
| 240 |
-
# Top-level scalar fields
|
| 241 |
-
self.d_single: int = kwargs.get("d_single", 384)
|
| 242 |
-
self.d_pair: int = kwargs.get("d_pair", 256)
|
| 243 |
-
self.n_relative_residx_bins: int = kwargs.get("n_relative_residx_bins", 32)
|
| 244 |
-
self.n_relative_chain_bins: int = kwargs.get("n_relative_chain_bins", 2)
|
| 245 |
-
self.num_loops: int = kwargs.get("num_loops", 10)
|
| 246 |
-
self.num_diffusion_samples: int = kwargs.get("num_diffusion_samples", 8)
|
| 247 |
-
# If True, ``profile`` / ``deletion_mean`` are zeroed before the inputs
|
| 248 |
-
# embedder.
|
| 249 |
-
self.disable_msa_features: bool = kwargs.get("disable_msa_features", False)
|
| 250 |
-
self.lm_dropout: float = kwargs.get("lm_dropout", 0.0)
|
| 251 |
self.force_lm_dropout_during_inference: bool = kwargs.get(
|
| 252 |
"force_lm_dropout_during_inference", False
|
| 253 |
)
|
|
|
|
| 254 |
|
| 255 |
self.lm_d_model: int = kwargs.get("lm_d_model", 2560)
|
| 256 |
-
self.lm_num_layers: int = kwargs.get("lm_num_layers", 80)
|
| 257 |
-
#
|
| 258 |
-
|
| 259 |
-
|
| 260 |
-
|
| 261 |
-
|
| 262 |
-
|
| 263 |
-
|
| 264 |
-
|
| 265 |
-
|
| 266 |
-
|
| 267 |
-
|
| 268 |
-
|
| 269 |
-
|
| 270 |
-
|
| 271 |
-
|
| 272 |
-
|
| 273 |
-
|
| 274 |
-
|
| 275 |
-
|
| 276 |
-
|
| 277 |
-
|
| 278 |
-
|
| 279 |
-
self.
|
| 280 |
-
|
| 281 |
-
|
| 282 |
-
self.
|
| 283 |
-
kwargs.get("
|
| 284 |
-
)
|
| 285 |
-
|
| 286 |
-
|
| 287 |
-
|
| 288 |
-
|
| 289 |
-
output
|
| 290 |
-
|
| 291 |
-
|
| 292 |
-
|
| 293 |
-
|
| 294 |
-
|
| 295 |
-
|
| 296 |
-
|
| 297 |
-
|
| 298 |
-
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Copyright 2026 Biohub. All rights reserved.
|
| 2 |
+
#
|
| 3 |
+
# Licensed under the Apache License, Version 2.0 (the "License");
|
| 4 |
+
# you may not use this file except in compliance with the License.
|
| 5 |
+
# You may obtain a copy of the License at
|
| 6 |
+
#
|
| 7 |
+
# http://www.apache.org/licenses/LICENSE-2.0
|
| 8 |
+
#
|
| 9 |
+
# Unless required by applicable law or agreed to in writing, software
|
| 10 |
+
# distributed under the License is distributed on an "AS IS" BASIS,
|
| 11 |
+
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
| 12 |
+
# See the License for the specific language governing permissions and
|
| 13 |
+
# limitations under the License.
|
| 14 |
+
"""ESMFold2 model configuration."""
|
| 15 |
+
|
| 16 |
+
from __future__ import annotations
|
| 17 |
+
|
| 18 |
+
from dataclasses import asdict, dataclass, field
|
| 19 |
+
|
| 20 |
+
from transformers.configuration_utils import PretrainedConfig
|
| 21 |
+
|
| 22 |
+
# ---------------------------------------------------------------------------
|
| 23 |
+
# Nested dataclass configs
|
| 24 |
+
# ---------------------------------------------------------------------------
|
| 25 |
+
|
| 26 |
+
_DEFAULT_ESMC_HF_REPO = "Synthyra/ESMplusplus_6B"
|
| 27 |
+
_DEFAULT_ESMC_ATTN_BACKEND = "flex"
|
| 28 |
+
_ESMC_ID_ALIASES = {
|
| 29 |
+
"biohub/ESMC-300M": "Synthyra/ESMplusplus_small",
|
| 30 |
+
"biohub/ESMC-600M": "Synthyra/ESMplusplus_large",
|
| 31 |
+
"biohub/ESMC-6B": "Synthyra/ESMplusplus_6B",
|
| 32 |
+
}
|
| 33 |
+
|
| 34 |
+
|
| 35 |
+
def normalize_esmc_id(esmc_id: str) -> str:
|
| 36 |
+
if esmc_id in _ESMC_ID_ALIASES:
|
| 37 |
+
return _ESMC_ID_ALIASES[esmc_id]
|
| 38 |
+
return esmc_id
|
| 39 |
+
|
| 40 |
+
|
| 41 |
+
@dataclass
|
| 42 |
+
class MSAEncoderConfig:
|
| 43 |
+
"""Config for the optional MSA encoder module (Large MSA models only)."""
|
| 44 |
+
|
| 45 |
+
enabled: bool = False
|
| 46 |
+
d_msa: int = 128
|
| 47 |
+
d_hidden: int = 32
|
| 48 |
+
n_layers: int = 4
|
| 49 |
+
n_heads_msa: int = 8
|
| 50 |
+
msa_head_width: int = 32
|
| 51 |
+
|
| 52 |
+
|
| 53 |
+
@dataclass
|
| 54 |
+
class ParcaeConfig:
|
| 55 |
+
"""Release-only config for the parcae diffusion-loop scheduler."""
|
| 56 |
+
|
| 57 |
+
enabled: bool = True
|
| 58 |
+
poisson_mean: float = 3.0
|
| 59 |
+
min_steps: int = 1
|
| 60 |
+
max_steps: int | None = 6
|
| 61 |
+
coda_n_layers: int = 2
|
| 62 |
+
|
| 63 |
+
|
| 64 |
+
@dataclass
|
| 65 |
+
class LMEncoderConfig:
|
| 66 |
+
"""Release-only config for the LM-side pair encoder."""
|
| 67 |
+
|
| 68 |
+
enabled: bool = True
|
| 69 |
+
n_layers: int = 4
|
| 70 |
+
lm_dropout: float = 0.25
|
| 71 |
+
per_loop_lm_dropout: bool = True
|
| 72 |
+
|
| 73 |
+
|
| 74 |
+
@dataclass
|
| 75 |
+
class AtomAttentionConfig:
|
| 76 |
+
"""Config for SWA atom encoder/decoder with 3D RoPE."""
|
| 77 |
+
|
| 78 |
+
d_atom: int = 128
|
| 79 |
+
d_token: int = 768
|
| 80 |
+
n_blocks: int = 3
|
| 81 |
+
n_heads: int = 4
|
| 82 |
+
swa_window_size: int = 128
|
| 83 |
+
expansion_ratio: int = 2
|
| 84 |
+
# 3D RoPE config
|
| 85 |
+
spatial_rope_base_frequency: float = 20.0
|
| 86 |
+
n_spatial_rope_pairs_per_axis: int = 2
|
| 87 |
+
n_uid_rope_pairs: int = 10
|
| 88 |
+
uid_rope_base_frequency: float = 10000.0
|
| 89 |
+
|
| 90 |
+
|
| 91 |
+
@dataclass
|
| 92 |
+
class FoldingTrunkConfig:
|
| 93 |
+
n_layers: int = 24
|
| 94 |
+
n_heads: int = 8
|
| 95 |
+
dropout: float = 0.0
|
| 96 |
+
|
| 97 |
+
|
| 98 |
+
@dataclass
|
| 99 |
+
class InputsEmbedderConfig:
|
| 100 |
+
d_inputs: int = 451
|
| 101 |
+
atom_encoder: AtomAttentionConfig = field(default_factory=AtomAttentionConfig)
|
| 102 |
+
|
| 103 |
+
def __post_init__(self):
|
| 104 |
+
if isinstance(self.atom_encoder, dict):
|
| 105 |
+
self.atom_encoder = AtomAttentionConfig(**self.atom_encoder)
|
| 106 |
+
|
| 107 |
+
|
| 108 |
+
@dataclass
|
| 109 |
+
class DiffusionModuleConfig:
|
| 110 |
+
"""Config for the DiffusionModule."""
|
| 111 |
+
|
| 112 |
+
sigma_data: float = 16.0
|
| 113 |
+
c_atom: int = 128
|
| 114 |
+
c_token: int = 768
|
| 115 |
+
c_z: int = 256
|
| 116 |
+
c_s_inputs: int = 451
|
| 117 |
+
fourier_dim: int = 256
|
| 118 |
+
relpos_r_max: int = 32
|
| 119 |
+
relpos_s_max: int = 2
|
| 120 |
+
atom_num_blocks: int = 3
|
| 121 |
+
atom_num_heads: int = 4
|
| 122 |
+
token_num_blocks: int = 12
|
| 123 |
+
token_num_heads: int = 16
|
| 124 |
+
transition_multiplier: int = 2
|
| 125 |
+
|
| 126 |
+
|
| 127 |
+
@dataclass
|
| 128 |
+
class DiffusionStructureHeadConfig:
|
| 129 |
+
"""Config for the diffusion-based structure prediction head."""
|
| 130 |
+
|
| 131 |
+
diffusion_module: DiffusionModuleConfig = field(
|
| 132 |
+
default_factory=DiffusionModuleConfig
|
| 133 |
+
)
|
| 134 |
+
distogram_bins: int = 128
|
| 135 |
+
|
| 136 |
+
# Training noise: sigma ~ sigma_data * exp(mu + sigma * N(0,1))
|
| 137 |
+
train_noise_log_mean: float = -1.2
|
| 138 |
+
train_noise_log_std: float = 1.5
|
| 139 |
+
|
| 140 |
+
# Sampling defaults (ODE)
|
| 141 |
+
gamma_0: float = 0.605
|
| 142 |
+
gamma_min: float = 1.107
|
| 143 |
+
noise_scale: float = 0.0
|
| 144 |
+
step_scale: float = 1.0
|
| 145 |
+
|
| 146 |
+
# Inference schedule defaults
|
| 147 |
+
inference_s_max: float = 160.0
|
| 148 |
+
inference_s_min: float = 4e-4
|
| 149 |
+
inference_p: float = 8.0
|
| 150 |
+
inference_num_steps: int = 68
|
| 151 |
+
|
| 152 |
+
def __post_init__(self):
|
| 153 |
+
if isinstance(self.diffusion_module, dict):
|
| 154 |
+
self.diffusion_module = DiffusionModuleConfig(**self.diffusion_module)
|
| 155 |
+
|
| 156 |
+
|
| 157 |
+
@dataclass
|
| 158 |
+
class ConfidenceHeadConfig:
|
| 159 |
+
enabled: bool = True
|
| 160 |
+
num_plddt_bins: int = 50
|
| 161 |
+
num_pde_bins: int = 64
|
| 162 |
+
num_pae_bins: int = 64
|
| 163 |
+
min_dist: float = 2.0
|
| 164 |
+
max_dist: float = 52.0
|
| 165 |
+
distogram_bins: int = 128
|
| 166 |
+
folding_trunk: FoldingTrunkConfig = field(
|
| 167 |
+
default_factory=lambda: FoldingTrunkConfig(n_layers=4)
|
| 168 |
+
)
|
| 169 |
+
|
| 170 |
+
def __post_init__(self):
|
| 171 |
+
if isinstance(self.folding_trunk, dict):
|
| 172 |
+
self.folding_trunk = FoldingTrunkConfig(**self.folding_trunk)
|
| 173 |
+
|
| 174 |
+
|
| 175 |
+
# ---------------------------------------------------------------------------
|
| 176 |
+
# Top-level config
|
| 177 |
+
# ---------------------------------------------------------------------------
|
| 178 |
+
|
| 179 |
+
|
| 180 |
+
class ESMFold2Config(PretrainedConfig):
|
| 181 |
+
"""
|
| 182 |
+
Configuration for the ESMFold2 structure prediction model.
|
| 183 |
+
|
| 184 |
+
Uses SWA atom encoders with 3D RoPE, a diffusion transformer,
|
| 185 |
+
a folding trunk, and an ESMC 6B PLM backbone.
|
| 186 |
+
|
| 187 |
+
Configuration objects inherit from [`PretrainedConfig`] and can be used to control
|
| 188 |
+
the model outputs. Read the documentation from [`PretrainedConfig`] for more
|
| 189 |
+
information.
|
| 190 |
+
|
| 191 |
+
Args:
|
| 192 |
+
d_single (`int`, defaults to 384):
|
| 193 |
+
Dimensionality of single (per-residue) representations.
|
| 194 |
+
d_pair (`int`, defaults to 256):
|
| 195 |
+
Dimensionality of pair (residue-residue) representations.
|
| 196 |
+
n_relative_residx_bins (`int`, defaults to 32):
|
| 197 |
+
Number of bins for relative residue index encoding.
|
| 198 |
+
n_relative_chain_bins (`int`, defaults to 2):
|
| 199 |
+
Number of bins for relative chain encoding.
|
| 200 |
+
num_loops (`int`, defaults to 10):
|
| 201 |
+
Number of trunk loops for iterative refinement.
|
| 202 |
+
num_diffusion_samples (`int`, defaults to 8):
|
| 203 |
+
Number of parallel structure predictions to generate.
|
| 204 |
lm_dropout (`float`, defaults to 0.0):
|
| 205 |
Dropout probability on LM pair embeddings. When > 0, dropout is
|
| 206 |
applied with ``training=True`` (including at inference) to match
|
|
|
|
| 208 |
force_lm_dropout_during_inference (`bool`, defaults to False):
|
| 209 |
When True, apply ``lm_dropout`` even when ``model.eval()`` and
|
| 210 |
``lm_dropout`` > 0. Binder-design loads set this to True.
|
| 211 |
+
lm_mask_pct (`float`, defaults to 0.0):
|
| 212 |
+
Fraction of LM residue tokens randomly replaced with the LM mask
|
| 213 |
+
token before running the PLM backbone.
|
| 214 |
disable_msa_features (`bool`, defaults to False):
|
| 215 |
When True, zero out MSA-derived ``profile`` and ``deletion_mean``
|
| 216 |
before the inputs embedder (experimental medium/large checkpoints).
|
| 217 |
+
inputs (`InputsEmbedderConfig`):
|
| 218 |
+
Configuration for the inputs embedder module.
|
| 219 |
+
folding_trunk (`FoldingTrunkConfig`):
|
| 220 |
+
Configuration for the folding trunk.
|
| 221 |
+
structure_head (`DiffusionStructureHeadConfig`):
|
| 222 |
+
Configuration for the diffusion-based structure prediction head.
|
| 223 |
+
confidence_head (`ConfidenceHeadConfig`):
|
| 224 |
+
Configuration for the confidence prediction head.
|
| 225 |
+
|
| 226 |
+
Examples:
|
| 227 |
+
|
| 228 |
+
```python
|
| 229 |
+
>>> from transformers import ESMFold2Config, ESMFold2ExperimentalModel
|
| 230 |
+
|
| 231 |
+
>>> # Initializing an ESMFold2 configuration
|
| 232 |
+
>>> configuration = ESMFold2Config(type="experimental")
|
| 233 |
+
|
| 234 |
+
>>> # Initializing a model (with random weights) from the configuration
|
| 235 |
+
>>> model = ESMFold2ExperimentalModel(configuration)
|
| 236 |
+
|
| 237 |
+
>>> # Accessing the model configuration
|
| 238 |
+
>>> configuration = model.config
|
| 239 |
+
```
|
| 240 |
+
"""
|
| 241 |
+
|
| 242 |
+
model_type = "esmfold2"
|
| 243 |
+
has_no_defaults_at_init = True
|
| 244 |
+
|
| 245 |
+
def __init__(self, **kwargs):
|
| 246 |
+
super().__init__(**kwargs)
|
| 247 |
+
|
| 248 |
+
self.type: str = kwargs.get("type", "release")
|
| 249 |
+
if self.type not in ("release", "experimental"):
|
| 250 |
+
raise ValueError(
|
| 251 |
+
f"ESMFold2Config.type must be 'release' or 'experimental', "
|
| 252 |
+
f"got {self.type!r}"
|
| 253 |
+
)
|
| 254 |
+
|
| 255 |
+
# Top-level scalar fields
|
| 256 |
+
self.d_single: int = kwargs.get("d_single", 384)
|
| 257 |
+
self.d_pair: int = kwargs.get("d_pair", 256)
|
| 258 |
+
self.n_relative_residx_bins: int = kwargs.get("n_relative_residx_bins", 32)
|
| 259 |
+
self.n_relative_chain_bins: int = kwargs.get("n_relative_chain_bins", 2)
|
| 260 |
+
self.num_loops: int = kwargs.get("num_loops", 10)
|
| 261 |
+
self.num_diffusion_samples: int = kwargs.get("num_diffusion_samples", 8)
|
| 262 |
+
# If True, ``profile`` / ``deletion_mean`` are zeroed before the inputs
|
| 263 |
+
# embedder.
|
| 264 |
+
self.disable_msa_features: bool = kwargs.get("disable_msa_features", False)
|
| 265 |
+
self.lm_dropout: float = kwargs.get("lm_dropout", 0.0)
|
| 266 |
self.force_lm_dropout_during_inference: bool = kwargs.get(
|
| 267 |
"force_lm_dropout_during_inference", False
|
| 268 |
)
|
| 269 |
+
self.lm_mask_pct: float = kwargs.get("lm_mask_pct", 0.0)
|
| 270 |
|
| 271 |
self.lm_d_model: int = kwargs.get("lm_d_model", 2560)
|
| 272 |
+
self.lm_num_layers: int = kwargs.get("lm_num_layers", 80)
|
| 273 |
+
# Backward-compatible field name; values now point to FastPLMs ESM++.
|
| 274 |
+
raw_esmc_id = (
|
| 275 |
+
kwargs["esmc_id"] if "esmc_id" in kwargs else _DEFAULT_ESMC_HF_REPO
|
| 276 |
+
)
|
| 277 |
+
self.esmc_id: str = normalize_esmc_id(raw_esmc_id)
|
| 278 |
+
self.esmc_attn_backend: str = (
|
| 279 |
+
kwargs["esmc_attn_backend"]
|
| 280 |
+
if "esmc_attn_backend" in kwargs
|
| 281 |
+
else _DEFAULT_ESMC_ATTN_BACKEND
|
| 282 |
+
)
|
| 283 |
+
|
| 284 |
+
def _init_nested(cls, val):
|
| 285 |
+
if isinstance(val, cls):
|
| 286 |
+
return val
|
| 287 |
+
if isinstance(val, dict):
|
| 288 |
+
return cls(**val)
|
| 289 |
+
return cls()
|
| 290 |
+
|
| 291 |
+
self.inputs = _init_nested(InputsEmbedderConfig, kwargs.get("inputs"))
|
| 292 |
+
self.folding_trunk = _init_nested(
|
| 293 |
+
FoldingTrunkConfig, kwargs.get("folding_trunk")
|
| 294 |
+
)
|
| 295 |
+
self.structure_head = _init_nested(
|
| 296 |
+
DiffusionStructureHeadConfig, kwargs.get("structure_head")
|
| 297 |
+
)
|
| 298 |
+
self.confidence_head = _init_nested(
|
| 299 |
+
ConfidenceHeadConfig, kwargs.get("confidence_head")
|
| 300 |
+
)
|
| 301 |
+
self.msa_encoder = _init_nested(MSAEncoderConfig, kwargs.get("msa_encoder"))
|
| 302 |
+
# Release-only modules — ignored when ``type == "experimental"``.
|
| 303 |
+
self.parcae = _init_nested(ParcaeConfig, kwargs.get("parcae"))
|
| 304 |
+
self.lm_encoder = _init_nested(LMEncoderConfig, kwargs.get("lm_encoder"))
|
| 305 |
+
# If True, MSA encoder output replaces the pair stream; if False, it is added.
|
| 306 |
+
self.msa_encoder_overwrite: bool = bool(
|
| 307 |
+
kwargs.get("msa_encoder_overwrite", True)
|
| 308 |
+
)
|
| 309 |
+
|
| 310 |
+
def to_dict(self):
|
| 311 |
+
output = super().to_dict()
|
| 312 |
+
output["inputs"] = asdict(self.inputs)
|
| 313 |
+
output["folding_trunk"] = asdict(self.folding_trunk)
|
| 314 |
+
output["structure_head"] = asdict(self.structure_head)
|
| 315 |
+
output["confidence_head"] = asdict(self.confidence_head)
|
| 316 |
+
output["msa_encoder"] = asdict(self.msa_encoder)
|
| 317 |
+
output["parcae"] = asdict(self.parcae)
|
| 318 |
+
output["lm_encoder"] = asdict(self.lm_encoder)
|
| 319 |
+
return output
|
| 320 |
+
|
| 321 |
+
|
| 322 |
+
__all__ = [
|
| 323 |
+
"ESMFold2Config",
|
| 324 |
+
"MSAEncoderConfig",
|
| 325 |
+
"ParcaeConfig",
|
| 326 |
+
"LMEncoderConfig",
|
| 327 |
+
"normalize_esmc_id",
|
| 328 |
+
]
|
esmfold2_affine3d.py
CHANGED
|
@@ -558,4 +558,3 @@ def build_affine3d_from_coordinates(
|
|
| 558 |
)
|
| 559 |
|
| 560 |
return affine, coord_mask
|
| 561 |
-
|
|
|
|
| 558 |
)
|
| 559 |
|
| 560 |
return affine, coord_mask
|
|
|
esmfold2_aligner.py
CHANGED
|
@@ -99,4 +99,3 @@ class Aligner:
|
|
| 99 |
aligned_atom37_positions[mobile.atom37_mask] = aligned_atom_tensor
|
| 100 |
|
| 101 |
return replace(mobile, atom37_positions=aligned_atom37_positions)
|
| 102 |
-
|
|
|
|
| 99 |
aligned_atom37_positions[mobile.atom37_mask] = aligned_atom_tensor
|
| 100 |
|
| 101 |
return replace(mobile, atom37_positions=aligned_atom37_positions)
|
|
|
esmfold2_atom_indexer.py
CHANGED
|
@@ -13,4 +13,3 @@ class AtomIndexer:
|
|
| 13 |
return index_by_atom_name(
|
| 14 |
getattr(self.structure, self.property), atom_names, self.dim
|
| 15 |
)
|
| 16 |
-
|
|
|
|
| 13 |
return index_by_atom_name(
|
| 14 |
getattr(self.structure, self.property), atom_names, self.dim
|
| 15 |
)
|
|
|
esmfold2_conformers.py
CHANGED
|
@@ -289,4 +289,3 @@ def get_ccd_leaving_atoms(comp_id: str) -> set[str]:
|
|
| 289 |
|
| 290 |
_CCD_LEAVING_ATOMS_CACHE[comp_id] = leaving_atoms
|
| 291 |
return leaving_atoms
|
| 292 |
-
|
|
|
|
| 289 |
|
| 290 |
_CCD_LEAVING_ATOMS_CACHE[comp_id] = leaving_atoms
|
| 291 |
return leaving_atoms
|
|
|
esmfold2_constants.py
CHANGED
|
@@ -560,4 +560,3 @@ RNA_BACKBONE_ATOMS = [
|
|
| 560 |
"O2'",
|
| 561 |
"C1'",
|
| 562 |
]
|
| 563 |
-
|
|
|
|
| 560 |
"O2'",
|
| 561 |
"C1'",
|
| 562 |
]
|
|
|
esmfold2_constants_esm3.py
CHANGED
|
@@ -135,4 +135,3 @@ KEYWORDS_IDF = IN_REPO_DATA_FOLDER / "keyword_idf_safety_filtered_58641.npy"
|
|
| 135 |
|
| 136 |
RESID_CSV = "data/uniref90_and_mgnify90_residue_annotations_gt_1k_proteins.csv"
|
| 137 |
INTERPRO2KEYWORDS = IN_REPO_DATA_FOLDER / "interpro_29026_to_keywords_58641.csv"
|
| 138 |
-
|
|
|
|
| 135 |
|
| 136 |
RESID_CSV = "data/uniref90_and_mgnify90_residue_annotations_gt_1k_proteins.csv"
|
| 137 |
INTERPRO2KEYWORDS = IN_REPO_DATA_FOLDER / "interpro_29026_to_keywords_58641.csv"
|
|
|
esmfold2_input_builder.py
CHANGED
|
@@ -252,4 +252,3 @@ def deserialize_structure_prediction_input(
|
|
| 252 |
distogram_conditioning=distogram_conditioning,
|
| 253 |
covalent_bonds=covalent_bonds,
|
| 254 |
)
|
| 255 |
-
|
|
|
|
| 252 |
distogram_conditioning=distogram_conditioning,
|
| 253 |
covalent_bonds=covalent_bonds,
|
| 254 |
)
|
|
|
esmfold2_metrics.py
CHANGED
|
@@ -5,7 +5,7 @@ from einops import rearrange
|
|
| 5 |
from torch import Tensor
|
| 6 |
from torch.amp import autocast # type: ignore
|
| 7 |
|
| 8 |
-
from . import esmfold2_residue_constants as residue_constants
|
| 9 |
from .esmfold2_misc import binpack, unbinpack
|
| 10 |
from .esmfold2_protein_structure import (
|
| 11 |
compute_alignment_tensors,
|
|
@@ -371,4 +371,3 @@ def compute_gdt_ts(
|
|
| 371 |
return compute_gdt_ts_no_alignment(
|
| 372 |
rotated_mobile, centered_target, atom_exists_mask, reduction
|
| 373 |
)
|
| 374 |
-
|
|
|
|
| 5 |
from torch import Tensor
|
| 6 |
from torch.amp import autocast # type: ignore
|
| 7 |
|
| 8 |
+
from . import esmfold2_residue_constants as residue_constants
|
| 9 |
from .esmfold2_misc import binpack, unbinpack
|
| 10 |
from .esmfold2_protein_structure import (
|
| 11 |
compute_alignment_tensors,
|
|
|
|
| 371 |
return compute_gdt_ts_no_alignment(
|
| 372 |
rotated_mobile, centered_target, atom_exists_mask, reduction
|
| 373 |
)
|
|
|
esmfold2_misc.py
CHANGED
|
@@ -502,4 +502,3 @@ def concat_objects(objs: Sequence[Any], separator: Any | None = None):
|
|
| 502 |
return torch.cat(objs) # type: ignore
|
| 503 |
case _:
|
| 504 |
raise TypeError(type(objs[0]))
|
| 505 |
-
|
|
|
|
| 502 |
return torch.cat(objs) # type: ignore
|
| 503 |
case _:
|
| 504 |
raise TypeError(type(objs[0]))
|
|
|
esmfold2_mmcif_parsing.py
CHANGED
|
@@ -10,7 +10,7 @@ from typing import Union
|
|
| 10 |
import biotite.structure as bs
|
| 11 |
import biotite.structure.io.pdbx as pdbx
|
| 12 |
|
| 13 |
-
from . import esmfold2_residue_constants as residue_constants
|
| 14 |
|
| 15 |
# Define PathOrBuffer for the opensource version
|
| 16 |
PathOrBuffer = Union[str, os.PathLike, io.StringIO]
|
|
@@ -467,4 +467,3 @@ class MmcifWrapper:
|
|
| 467 |
return self._parse_nonpoly_from_mmcif()
|
| 468 |
except Exception:
|
| 469 |
return self._parse_nonpoly_fallback()
|
| 470 |
-
|
|
|
|
| 10 |
import biotite.structure as bs
|
| 11 |
import biotite.structure.io.pdbx as pdbx
|
| 12 |
|
| 13 |
+
from . import esmfold2_residue_constants as residue_constants
|
| 14 |
|
| 15 |
# Define PathOrBuffer for the opensource version
|
| 16 |
PathOrBuffer = Union[str, os.PathLike, io.StringIO]
|
|
|
|
| 467 |
return self._parse_nonpoly_from_mmcif()
|
| 468 |
except Exception:
|
| 469 |
return self._parse_nonpoly_fallback()
|
|
|
esmfold2_molecular_complex.py
CHANGED
|
@@ -23,7 +23,7 @@ from biotite.structure.io.pdbx import (
|
|
| 23 |
set_structure,
|
| 24 |
)
|
| 25 |
|
| 26 |
-
from . import esmfold2_residue_constants as residue_constants
|
| 27 |
from .esmfold2_metrics import compute_lddt, compute_rmsd
|
| 28 |
from .esmfold2_protein_complex import ProteinComplex, ProteinComplexMetadata
|
| 29 |
|
|
@@ -44,6 +44,7 @@ class MolecularComplexResult:
|
|
| 44 |
residue_index: torch.Tensor | None = None
|
| 45 |
entity_id: torch.Tensor | None = None
|
| 46 |
sae_features: np.ndarray | None = None # [L, n_features]
|
|
|
|
| 47 |
|
| 48 |
|
| 49 |
@dataclass
|
|
@@ -1223,4 +1224,3 @@ class MolecularComplex:
|
|
| 1223 |
return cls.from_state_dict(
|
| 1224 |
msgpack.loads(brotli.decompress(bytes), strict_map_key=False)
|
| 1225 |
)
|
| 1226 |
-
|
|
|
|
| 23 |
set_structure,
|
| 24 |
)
|
| 25 |
|
| 26 |
+
from . import esmfold2_residue_constants as residue_constants
|
| 27 |
from .esmfold2_metrics import compute_lddt, compute_rmsd
|
| 28 |
from .esmfold2_protein_complex import ProteinComplex, ProteinComplexMetadata
|
| 29 |
|
|
|
|
| 44 |
residue_index: torch.Tensor | None = None
|
| 45 |
entity_id: torch.Tensor | None = None
|
| 46 |
sae_features: np.ndarray | None = None # [L, n_features]
|
| 47 |
+
ttt_metrics: dict[str, Any] | None = None
|
| 48 |
|
| 49 |
|
| 50 |
@dataclass
|
|
|
|
| 1224 |
return cls.from_state_dict(
|
| 1225 |
msgpack.loads(brotli.decompress(bytes), strict_map_key=False)
|
| 1226 |
)
|
|
|
esmfold2_msa.py
CHANGED
|
@@ -504,4 +504,3 @@ class FastMSA(SequentialDataclass):
|
|
| 504 |
if headers is not None:
|
| 505 |
all_headers.extend(headers)
|
| 506 |
return cls(np.concatenate(arrays, axis=0), all_headers)
|
| 507 |
-
|
|
|
|
| 504 |
if headers is not None:
|
| 505 |
all_headers.extend(headers)
|
| 506 |
return cls(np.concatenate(arrays, axis=0), all_headers)
|
|
|
esmfold2_msa_filter_sequences.py
CHANGED
|
@@ -80,4 +80,3 @@ def hhfilter(
|
|
| 80 |
with output_file.open() as f:
|
| 81 |
indices = [int(line[1:].strip()) for line in f if line.startswith(">")]
|
| 82 |
return indices
|
| 83 |
-
|
|
|
|
| 80 |
with output_file.open() as f:
|
| 81 |
indices = [int(line[1:].strip()) for line in f if line.startswith(">")]
|
| 82 |
return indices
|
|
|
esmfold2_normalize_coordinates.py
CHANGED
|
@@ -77,4 +77,3 @@ def apply_frame_to_coords(coords: Tensor, frame: Affine3D) -> Tensor:
|
|
| 77 |
|
| 78 |
def normalize_coordinates(coords: Tensor) -> Tensor:
|
| 79 |
return apply_frame_to_coords(coords, get_protein_normalization_frame(coords))
|
| 80 |
-
|
|
|
|
| 77 |
|
| 78 |
def normalize_coordinates(coords: Tensor) -> Tensor:
|
| 79 |
return apply_frame_to_coords(coords, get_protein_normalization_frame(coords))
|
|
|
esmfold2_output.py
CHANGED
|
@@ -222,4 +222,3 @@ def build_molecular_complex(
|
|
| 222 |
assembly_composition=None,
|
| 223 |
),
|
| 224 |
)
|
| 225 |
-
|
|
|
|
| 222 |
assembly_composition=None,
|
| 223 |
),
|
| 224 |
)
|
|
|
esmfold2_paired_msa.py
CHANGED
|
@@ -243,4 +243,3 @@ def construct_paired_msa(
|
|
| 243 |
paired_mask[:, token_mask] = chain_paired[:, None]
|
| 244 |
|
| 245 |
return msa_residues, deletion_value, paired_mask
|
| 246 |
-
|
|
|
|
| 243 |
paired_mask[:, token_mask] = chain_paired[:, None]
|
| 244 |
|
| 245 |
return msa_residues, deletion_value, paired_mask
|
|
|
esmfold2_parsing.py
CHANGED
|
@@ -110,4 +110,3 @@ def write_sequences(sequences: Iterable[tuple[str, str]], path: PathOrBuffer) ->
|
|
| 110 |
finally:
|
| 111 |
if needs_closing:
|
| 112 |
handle.close() # type: ignore
|
| 113 |
-
|
|
|
|
| 110 |
finally:
|
| 111 |
if needs_closing:
|
| 112 |
handle.close() # type: ignore
|
|
|
esmfold2_predicted_aligned_error.py
CHANGED
|
@@ -102,4 +102,3 @@ def tm_loss(
|
|
| 102 |
loss = loss.mean()
|
| 103 |
|
| 104 |
return loss
|
| 105 |
-
|
|
|
|
| 102 |
loss = loss.mean()
|
| 103 |
|
| 104 |
return loss
|
|
|
esmfold2_prepare_input.py
CHANGED
|
@@ -1461,4 +1461,3 @@ def prepare_esmfold2_input(
|
|
| 1461 |
chains, tokens, atoms = build_chains_from_input(input, seed)
|
| 1462 |
features = build_feature_tensors(chains, tokens, atoms, input)
|
| 1463 |
return features, chains
|
| 1464 |
-
|
|
|
|
| 1461 |
chains, tokens, atoms = build_chains_from_input(input, seed)
|
| 1462 |
features = build_feature_tensors(chains, tokens, atoms, input)
|
| 1463 |
return features, chains
|
|
|
esmfold2_processor.py
CHANGED
|
@@ -353,4 +353,3 @@ class ESMFold2InputBuilder:
|
|
| 353 |
|
| 354 |
|
| 355 |
__all__ = ["ESMFold2InputBuilder", "clean_esmfold2_input"]
|
| 356 |
-
|
|
|
|
| 353 |
|
| 354 |
|
| 355 |
__all__ = ["ESMFold2InputBuilder", "clean_esmfold2_input"]
|
|
|
esmfold2_protein_chain.py
CHANGED
|
@@ -20,7 +20,7 @@ from biotite.structure.io.pdbx import set_structure as set_structure_pdbx
|
|
| 20 |
from scipy.spatial import ConvexHull, KDTree
|
| 21 |
from scipy.spatial.distance import cdist, pdist, squareform
|
| 22 |
|
| 23 |
-
from . import esmfold2_residue_constants as residue_constants
|
| 24 |
from .esmfold2_misc import slice_python_object_as_numpy
|
| 25 |
from .esmfold2_affine3d import Affine3D
|
| 26 |
from .esmfold2_aligner import Aligner
|
|
@@ -1373,4 +1373,3 @@ class ProteinChain:
|
|
| 1373 |
) # (1, L)
|
| 1374 |
|
| 1375 |
return coordinates, plddt, residue_index
|
| 1376 |
-
|
|
|
|
| 20 |
from scipy.spatial import ConvexHull, KDTree
|
| 21 |
from scipy.spatial.distance import cdist, pdist, squareform
|
| 22 |
|
| 23 |
+
from . import esmfold2_residue_constants as residue_constants
|
| 24 |
from .esmfold2_misc import slice_python_object_as_numpy
|
| 25 |
from .esmfold2_affine3d import Affine3D
|
| 26 |
from .esmfold2_aligner import Aligner
|
|
|
|
| 1373 |
) # (1, L)
|
| 1374 |
|
| 1375 |
return coordinates, plddt, residue_index
|
|
|
esmfold2_protein_complex.py
CHANGED
|
@@ -27,7 +27,7 @@ from biotite.structure.io.pdbx.convert import _get_transformations, get_structur
|
|
| 27 |
from biotite.structure.util import matrix_rotate
|
| 28 |
from scipy.spatial import KDTree
|
| 29 |
|
| 30 |
-
from . import esmfold2_residue_constants as residue_constants
|
| 31 |
from .esmfold2_misc import slice_python_object_as_numpy
|
| 32 |
from .esmfold2_affine3d import Affine3D
|
| 33 |
from .esmfold2_aligner import Aligner
|
|
@@ -1238,4 +1238,3 @@ def protein_chain_to_protein_complex(chain: ProteinChain) -> ProteinComplex:
|
|
| 1238 |
for i, chain in enumerate(complex_chains)
|
| 1239 |
]
|
| 1240 |
return ProteinComplex.from_chains(complex_chains)
|
| 1241 |
-
|
|
|
|
| 27 |
from biotite.structure.util import matrix_rotate
|
| 28 |
from scipy.spatial import KDTree
|
| 29 |
|
| 30 |
+
from . import esmfold2_residue_constants as residue_constants
|
| 31 |
from .esmfold2_misc import slice_python_object_as_numpy
|
| 32 |
from .esmfold2_affine3d import Affine3D
|
| 33 |
from .esmfold2_aligner import Aligner
|
|
|
|
| 1238 |
for i, chain in enumerate(complex_chains)
|
| 1239 |
]
|
| 1240 |
return ProteinComplex.from_chains(complex_chains)
|
|
|
esmfold2_protein_structure.py
CHANGED
|
@@ -8,7 +8,7 @@ import torch.nn.functional as F
|
|
| 8 |
from torch import Tensor
|
| 9 |
from torch.amp import autocast # type: ignore
|
| 10 |
|
| 11 |
-
from . import esmfold2_residue_constants as residue_constants
|
| 12 |
from .esmfold2_misc import unbinpack
|
| 13 |
from .esmfold2_affine3d import Affine3D
|
| 14 |
|
|
@@ -304,4 +304,3 @@ def compute_gdt_ts_no_alignment(
|
|
| 304 |
return score
|
| 305 |
else:
|
| 306 |
raise ValueError("Unrecognized reduction: '{reduction}'")
|
| 307 |
-
|
|
|
|
| 8 |
from torch import Tensor
|
| 9 |
from torch.amp import autocast # type: ignore
|
| 10 |
|
| 11 |
+
from . import esmfold2_residue_constants as residue_constants
|
| 12 |
from .esmfold2_misc import unbinpack
|
| 13 |
from .esmfold2_affine3d import Affine3D
|
| 14 |
|
|
|
|
| 304 |
return score
|
| 305 |
else:
|
| 306 |
raise ValueError("Unrecognized reduction: '{reduction}'")
|
|
|
esmfold2_residue_constants.py
CHANGED
|
@@ -1221,4 +1221,3 @@ def _make_restype_atom14_to_atom37():
|
|
| 1221 |
RESTYPE_ATOM14_TO_ATOM37 = _make_restype_atom14_to_atom37()
|
| 1222 |
RESTYPE_ATOM37_TO_ATOM14 = _make_restype_atom37_to_atom14()
|
| 1223 |
CHAIN_BREAK_TOKEN = "|"
|
| 1224 |
-
|
|
|
|
| 1221 |
RESTYPE_ATOM14_TO_ATOM37 = _make_restype_atom14_to_atom37()
|
| 1222 |
RESTYPE_ATOM37_TO_ATOM14 = _make_restype_atom37_to_atom14()
|
| 1223 |
CHAIN_BREAK_TOKEN = "|"
|
|
|
esmfold2_sequential_dataclass.py
CHANGED
|
@@ -155,4 +155,3 @@ class SequentialDataclass(ABC):
|
|
| 155 |
items[0], # type: ignore
|
| 156 |
**updated_fields,
|
| 157 |
)
|
| 158 |
-
|
|
|
|
| 155 |
items[0], # type: ignore
|
| 156 |
**updated_fields,
|
| 157 |
)
|
|
|
esmfold2_system.py
CHANGED
|
@@ -43,4 +43,3 @@ def run_subprocess_with_errorcheck(
|
|
| 43 |
f"Command failed with errorcode {e.returncode}." f"\n\n{e.stderr.decode()}"
|
| 44 |
)
|
| 45 |
return p
|
| 46 |
-
|
|
|
|
| 43 |
f"Command failed with errorcode {e.returncode}." f"\n\n{e.stderr.decode()}"
|
| 44 |
)
|
| 45 |
return p
|
|
|
esmfold2_types.py
CHANGED
|
@@ -31,4 +31,3 @@ __all__ = [
|
|
| 31 |
"CovalentBond",
|
| 32 |
"StructurePredictionInput",
|
| 33 |
]
|
| 34 |
-
|
|
|
|
| 31 |
"CovalentBond",
|
| 32 |
"StructurePredictionInput",
|
| 33 |
]
|
|
|
esmfold2_utils_types.py
CHANGED
|
@@ -31,4 +31,3 @@ class FunctionAnnotation:
|
|
| 31 |
def __len__(self) -> int:
|
| 32 |
"""Length of the annotation."""
|
| 33 |
return self.end - self.start + 1
|
| 34 |
-
|
|
|
|
| 31 |
def __len__(self) -> int:
|
| 32 |
"""Length of the annotation."""
|
| 33 |
return self.end - self.start + 1
|
|
|
modeling_esmfold2.py
CHANGED
|
The diff for this file is too large to render.
See raw diff
|
|
|
modeling_esmfold2_common.py
CHANGED
|
The diff for this file is too large to render.
See raw diff
|
|
|
modeling_esmfold2_experimental.py
ADDED
|
@@ -0,0 +1,1001 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""FastPLMs ESMFold2 experimental architecture.
|
| 2 |
+
|
| 3 |
+
This module supports Biohub's experimental binder-design checkpoints. The
|
| 4 |
+
released ESMFold2 architecture in ``modeling_esmfold2.py`` intentionally
|
| 5 |
+
rejects those configs because the experimental trunk uses explicit pair-loop
|
| 6 |
+
re-injection and a different confidence/MSA stack.
|
| 7 |
+
"""
|
| 8 |
+
|
| 9 |
+
from __future__ import annotations
|
| 10 |
+
|
| 11 |
+
import math
|
| 12 |
+
from pathlib import Path
|
| 13 |
+
from typing import Any, cast
|
| 14 |
+
|
| 15 |
+
import torch
|
| 16 |
+
import torch.nn as nn
|
| 17 |
+
import torch.nn.functional as F
|
| 18 |
+
from torch import Tensor
|
| 19 |
+
from transformers.modeling_utils import PreTrainedModel
|
| 20 |
+
|
| 21 |
+
from .configuration_esmfold2 import ESMFold2Config
|
| 22 |
+
from .modeling_esmfold2 import (
|
| 23 |
+
_load_fastplms_esmplusplus_for_esmfold2,
|
| 24 |
+
_lm_precision_context,
|
| 25 |
+
)
|
| 26 |
+
from .modeling_esmfold2_common import (
|
| 27 |
+
CHAR_VOCAB_SIZE,
|
| 28 |
+
MAX_ATOMIC_NUMBER,
|
| 29 |
+
NUM_RES_TYPES,
|
| 30 |
+
DiffusionModule,
|
| 31 |
+
DiffusionStructureHead,
|
| 32 |
+
DiffusionTransformer,
|
| 33 |
+
FoldingTrunk,
|
| 34 |
+
InputsEmbedder,
|
| 35 |
+
LanguageModelShim,
|
| 36 |
+
MSAPairWeightedAveraging,
|
| 37 |
+
OuterProductMean,
|
| 38 |
+
PairUpdateBlock,
|
| 39 |
+
ResIdxAsymIdSymIdEntityIdEncoding,
|
| 40 |
+
RowAttentionPooling,
|
| 41 |
+
SwiGLUMLP,
|
| 42 |
+
TriangleMultiplicativeUpdate,
|
| 43 |
+
_categorical_mean,
|
| 44 |
+
_compute_intra_token_idx,
|
| 45 |
+
_seed_context,
|
| 46 |
+
compute_lm_hidden_states,
|
| 47 |
+
gather_rep_atom_coords,
|
| 48 |
+
gather_token_to_atom,
|
| 49 |
+
)
|
| 50 |
+
|
| 51 |
+
_EPS = 1e-5
|
| 52 |
+
_NONPOLYMER_ID = 3
|
| 53 |
+
|
| 54 |
+
|
| 55 |
+
class ConfidenceHead(nn.Module):
|
| 56 |
+
"""Experimental confidence head predicting pLDDT, PAE, pTM, and ipTM."""
|
| 57 |
+
|
| 58 |
+
boundaries: Tensor
|
| 59 |
+
|
| 60 |
+
def __init__(self, config: ESMFold2Config) -> None:
|
| 61 |
+
super().__init__()
|
| 62 |
+
ch = config.confidence_head
|
| 63 |
+
d_single = config.d_single
|
| 64 |
+
d_pair = config.d_pair
|
| 65 |
+
d_inputs = config.inputs.d_inputs
|
| 66 |
+
|
| 67 |
+
boundaries = torch.linspace(ch.min_dist, ch.max_dist, ch.distogram_bins - 1)
|
| 68 |
+
self.register_buffer("boundaries", boundaries)
|
| 69 |
+
self.dist_bin_pairwise_embed = nn.Embedding(ch.distogram_bins, d_pair)
|
| 70 |
+
|
| 71 |
+
self.s_norm = nn.LayerNorm(d_single)
|
| 72 |
+
self.s_inputs_to_single = nn.Linear(d_inputs, d_single, bias=False)
|
| 73 |
+
self.s_to_z = nn.Linear(d_inputs, d_pair, bias=False)
|
| 74 |
+
self.s_to_z_transpose = nn.Linear(d_inputs, d_pair, bias=False)
|
| 75 |
+
self.s_to_z_prod_in1 = nn.Linear(d_inputs, d_pair, bias=False)
|
| 76 |
+
self.s_to_z_prod_in2 = nn.Linear(d_inputs, d_pair, bias=False)
|
| 77 |
+
self.s_to_z_prod_out = nn.Linear(d_pair, d_pair, bias=False)
|
| 78 |
+
self.s_input_to_s = nn.Linear(d_inputs, d_single, bias=False)
|
| 79 |
+
self.s_inputs_norm = nn.LayerNorm(d_inputs)
|
| 80 |
+
self.z_norm = nn.LayerNorm(d_pair)
|
| 81 |
+
self.row_attention_pooling = RowAttentionPooling(
|
| 82 |
+
d_pair=d_pair, d_single=d_single
|
| 83 |
+
)
|
| 84 |
+
|
| 85 |
+
pf = ch.folding_trunk
|
| 86 |
+
self.folding_trunk = FoldingTrunk(
|
| 87 |
+
n_layers=pf.n_layers, d_pair=d_pair, expansion_ratio=4
|
| 88 |
+
)
|
| 89 |
+
|
| 90 |
+
self.plddt_ln = nn.LayerNorm(d_single)
|
| 91 |
+
max_atoms_per_token = 23
|
| 92 |
+
self.plddt_weight = nn.Parameter(
|
| 93 |
+
torch.zeros(max_atoms_per_token, d_single, ch.num_plddt_bins)
|
| 94 |
+
)
|
| 95 |
+
self.pae_head = nn.Linear(d_pair, ch.num_pae_bins, bias=False)
|
| 96 |
+
|
| 97 |
+
def set_kernel_backend(self, backend: str | None) -> None:
|
| 98 |
+
self.folding_trunk.set_kernel_backend(backend)
|
| 99 |
+
|
| 100 |
+
def set_chunk_size(self, chunk_size: int | None) -> None:
|
| 101 |
+
self.folding_trunk.set_chunk_size(chunk_size)
|
| 102 |
+
|
| 103 |
+
@staticmethod
|
| 104 |
+
def _repeat_batch(x: Tensor, num_diffusion_samples: int) -> Tensor:
|
| 105 |
+
if num_diffusion_samples == 1:
|
| 106 |
+
return x
|
| 107 |
+
return x.repeat_interleave(num_diffusion_samples, 0)
|
| 108 |
+
|
| 109 |
+
@staticmethod
|
| 110 |
+
def _flatten_sample_axis(x: Tensor) -> Tensor:
|
| 111 |
+
if x.ndim == 4:
|
| 112 |
+
b, mult, n, c = x.shape
|
| 113 |
+
return x.reshape(b * mult, n, c)
|
| 114 |
+
return x
|
| 115 |
+
|
| 116 |
+
def forward(
|
| 117 |
+
self,
|
| 118 |
+
s_inputs: Tensor,
|
| 119 |
+
z: Tensor,
|
| 120 |
+
x_pred: Tensor,
|
| 121 |
+
distogram_atom_idx: Tensor,
|
| 122 |
+
token_attention_mask: Tensor,
|
| 123 |
+
atom_to_token: Tensor,
|
| 124 |
+
atom_attention_mask: Tensor,
|
| 125 |
+
asym_id: Tensor,
|
| 126 |
+
mol_type: Tensor,
|
| 127 |
+
num_diffusion_samples: int = 1,
|
| 128 |
+
relative_position_encoding: Tensor | None = None,
|
| 129 |
+
token_bonds_encoding: Tensor | None = None,
|
| 130 |
+
) -> dict[str, Tensor]:
|
| 131 |
+
s_inputs_normed = self.s_inputs_norm(s_inputs)
|
| 132 |
+
z_base = self.z_norm(z)
|
| 133 |
+
if relative_position_encoding is not None:
|
| 134 |
+
z_base = z_base + relative_position_encoding
|
| 135 |
+
if token_bonds_encoding is not None:
|
| 136 |
+
z_base = z_base + token_bonds_encoding
|
| 137 |
+
z_base = z_base + self.s_to_z(s_inputs_normed).unsqueeze(2)
|
| 138 |
+
z_base = z_base + self.s_to_z_transpose(s_inputs_normed).unsqueeze(1)
|
| 139 |
+
z_base = z_base + self.s_to_z_prod_out(
|
| 140 |
+
self.s_to_z_prod_in1(s_inputs_normed)[:, :, None, :]
|
| 141 |
+
* self.s_to_z_prod_in2(s_inputs_normed)[:, None, :, :]
|
| 142 |
+
)
|
| 143 |
+
|
| 144 |
+
pair = self._repeat_batch(z_base, num_diffusion_samples)
|
| 145 |
+
x_pred_flat = self._flatten_sample_axis(x_pred)
|
| 146 |
+
atom_to_token_m = self._repeat_batch(atom_to_token, num_diffusion_samples)
|
| 147 |
+
atom_mask_m = self._repeat_batch(atom_attention_mask, num_diffusion_samples)
|
| 148 |
+
rep_idx_m = self._repeat_batch(distogram_atom_idx, num_diffusion_samples).long()
|
| 149 |
+
mask = self._repeat_batch(token_attention_mask, num_diffusion_samples)
|
| 150 |
+
batch_mult = pair.shape[0]
|
| 151 |
+
|
| 152 |
+
rep_coords = gather_rep_atom_coords(x_pred_flat, rep_idx_m)
|
| 153 |
+
rep_distances = torch.cdist(
|
| 154 |
+
rep_coords, rep_coords, compute_mode="donot_use_mm_for_euclid_dist"
|
| 155 |
+
)
|
| 156 |
+
distogram_bins = (
|
| 157 |
+
(rep_distances.unsqueeze(-1) > self.boundaries).sum(dim=-1).long()
|
| 158 |
+
)
|
| 159 |
+
pair = pair + self.dist_bin_pairwise_embed(distogram_bins)
|
| 160 |
+
|
| 161 |
+
pair_mask = mask[:, :, None].float() * mask[:, None, :].float()
|
| 162 |
+
pair = pair + self.folding_trunk(pair, pair_attention_mask=pair_mask)
|
| 163 |
+
single = self.row_attention_pooling(pair, mask)
|
| 164 |
+
|
| 165 |
+
atom_mask_f = atom_mask_m.float()
|
| 166 |
+
s_at_atoms = gather_token_to_atom(single, atom_to_token_m)
|
| 167 |
+
s_at_atoms = self.plddt_ln(s_at_atoms)
|
| 168 |
+
intra_idx = _compute_intra_token_idx(atom_to_token_m)
|
| 169 |
+
intra_idx = intra_idx.clamp(max=self.plddt_weight.shape[0] - 1)
|
| 170 |
+
plddt_weight = self.plddt_weight[intra_idx]
|
| 171 |
+
plddt_logits = torch.einsum("...c,...cb->...b", s_at_atoms, plddt_weight)
|
| 172 |
+
plddt_per_atom = _categorical_mean(plddt_logits, start=0.0, end=1.0)
|
| 173 |
+
|
| 174 |
+
length = single.shape[1]
|
| 175 |
+
plddt_sum = torch.zeros(
|
| 176 |
+
batch_mult, length, device=single.device, dtype=plddt_per_atom.dtype
|
| 177 |
+
)
|
| 178 |
+
atom_count = torch.zeros(
|
| 179 |
+
batch_mult, length, device=single.device, dtype=plddt_per_atom.dtype
|
| 180 |
+
)
|
| 181 |
+
atom_mask_t = atom_mask_f.to(plddt_per_atom.dtype)
|
| 182 |
+
plddt_sum.scatter_add_(1, atom_to_token_m, plddt_per_atom * atom_mask_t)
|
| 183 |
+
atom_count.scatter_add_(1, atom_to_token_m, atom_mask_t)
|
| 184 |
+
plddt = plddt_sum / atom_count.clamp(min=1e-6)
|
| 185 |
+
|
| 186 |
+
complex_plddt = (plddt_per_atom * atom_mask_f).sum(dim=-1) / (
|
| 187 |
+
atom_mask_f.sum(dim=-1) + _EPS
|
| 188 |
+
)
|
| 189 |
+
|
| 190 |
+
expanded_type = self._repeat_batch(mol_type, num_diffusion_samples)
|
| 191 |
+
expanded_asym = self._repeat_batch(asym_id, num_diffusion_samples)
|
| 192 |
+
is_ligand = (expanded_type == _NONPOLYMER_ID).float()
|
| 193 |
+
inter_chain = (
|
| 194 |
+
expanded_asym.unsqueeze(-1) != expanded_asym.unsqueeze(-2)
|
| 195 |
+
).float()
|
| 196 |
+
near_contact = (rep_distances < 8).float()
|
| 197 |
+
interface_per_token = (
|
| 198 |
+
near_contact * inter_chain * (1.0 - is_ligand).unsqueeze(-1)
|
| 199 |
+
).amax(dim=-1)
|
| 200 |
+
iplddt_weight = torch.where(
|
| 201 |
+
is_ligand.bool(),
|
| 202 |
+
torch.full_like(interface_per_token, 2.0),
|
| 203 |
+
interface_per_token,
|
| 204 |
+
)
|
| 205 |
+
iplddt_weight_atoms = gather_token_to_atom(
|
| 206 |
+
iplddt_weight.unsqueeze(-1), atom_to_token_m
|
| 207 |
+
).squeeze(-1)
|
| 208 |
+
atom_iplddt_w = atom_mask_f * iplddt_weight_atoms
|
| 209 |
+
complex_iplddt = (plddt_per_atom * atom_iplddt_w).sum(dim=-1) / (
|
| 210 |
+
atom_iplddt_w.sum(dim=-1) + _EPS
|
| 211 |
+
)
|
| 212 |
+
plddt_ca = plddt_per_atom.gather(1, rep_idx_m)
|
| 213 |
+
|
| 214 |
+
pae_logits = self.pae_head(pair)
|
| 215 |
+
pae = _categorical_mean(pae_logits, start=0.0, end=32.0).detach()
|
| 216 |
+
|
| 217 |
+
n_bins = pae_logits.shape[-1]
|
| 218 |
+
bin_width = 32.0 / n_bins
|
| 219 |
+
bin_centers = torch.arange(
|
| 220 |
+
0.5 * bin_width, 32.0, bin_width, device=pae_logits.device
|
| 221 |
+
)
|
| 222 |
+
mask_f = mask.float()
|
| 223 |
+
n_res = mask_f.sum(dim=-1, keepdim=True)
|
| 224 |
+
d0 = 1.24 * (n_res.clamp(min=19) - 15) ** (1 / 3) - 1.8
|
| 225 |
+
tm_per_bin = 1 / (1 + (bin_centers / d0) ** 2)
|
| 226 |
+
pae_probs = F.softmax(pae_logits, dim=-1)
|
| 227 |
+
tm_expected = (pae_probs * tm_per_bin[:, None, None, :]).sum(dim=-1)
|
| 228 |
+
|
| 229 |
+
pair_mask_2d = mask_f.unsqueeze(-1) * mask_f.unsqueeze(-2)
|
| 230 |
+
ptm_per_row = (tm_expected * pair_mask_2d).sum(dim=-1) / (
|
| 231 |
+
pair_mask_2d.sum(dim=-1) + _EPS
|
| 232 |
+
)
|
| 233 |
+
ptm = ptm_per_row.max(dim=-1).values
|
| 234 |
+
|
| 235 |
+
inter_chain_mask = (
|
| 236 |
+
expanded_asym.unsqueeze(-1) != expanded_asym.unsqueeze(-2)
|
| 237 |
+
).float() * pair_mask_2d
|
| 238 |
+
iptm_per_row = (tm_expected * inter_chain_mask).sum(dim=-1) / (
|
| 239 |
+
inter_chain_mask.sum(dim=-1) + _EPS
|
| 240 |
+
)
|
| 241 |
+
iptm = iptm_per_row.max(dim=-1).values
|
| 242 |
+
|
| 243 |
+
max_chain_id = int(expanded_asym.max().item()) if batch_mult > 0 else 0
|
| 244 |
+
n_chains = max_chain_id + 1
|
| 245 |
+
pair_chains_iptm = torch.zeros(
|
| 246 |
+
batch_mult,
|
| 247 |
+
n_chains,
|
| 248 |
+
n_chains,
|
| 249 |
+
device=tm_expected.device,
|
| 250 |
+
dtype=tm_expected.dtype,
|
| 251 |
+
)
|
| 252 |
+
for c1 in range(n_chains):
|
| 253 |
+
chain_c1 = (expanded_asym == c1).float() * mask_f
|
| 254 |
+
if chain_c1.sum() == 0:
|
| 255 |
+
continue
|
| 256 |
+
for c2 in range(n_chains):
|
| 257 |
+
chain_c2 = (expanded_asym == c2).float() * mask_f
|
| 258 |
+
pair_m = chain_c1.unsqueeze(-1) * chain_c2.unsqueeze(-2)
|
| 259 |
+
denom = pair_m.sum(dim=(-1, -2)) + _EPS
|
| 260 |
+
pair_chains_iptm[:, c1, c2] = (tm_expected * pair_m).sum(
|
| 261 |
+
dim=(-1, -2)
|
| 262 |
+
) / denom
|
| 263 |
+
|
| 264 |
+
return {
|
| 265 |
+
"plddt_logits": plddt_logits,
|
| 266 |
+
"plddt": plddt.detach(),
|
| 267 |
+
"plddt_per_atom": plddt_per_atom.detach(),
|
| 268 |
+
"plddt_ca": plddt_ca.detach(),
|
| 269 |
+
"complex_plddt": complex_plddt.detach(),
|
| 270 |
+
"complex_iplddt": complex_iplddt.detach(),
|
| 271 |
+
"pae_logits": pae_logits,
|
| 272 |
+
"pae": pae,
|
| 273 |
+
"ptm": ptm.detach(),
|
| 274 |
+
"iptm": iptm.detach(),
|
| 275 |
+
"pair_chains_iptm": pair_chains_iptm.detach(),
|
| 276 |
+
}
|
| 277 |
+
|
| 278 |
+
|
| 279 |
+
class _TransitionFFN(nn.Module):
|
| 280 |
+
def __init__(self, d_model: int, expansion_ratio: int = 4) -> None:
|
| 281 |
+
super().__init__()
|
| 282 |
+
self.norm = nn.LayerNorm(d_model)
|
| 283 |
+
self.ffn = SwiGLUMLP(d_model, expansion_ratio=expansion_ratio, bias=False)
|
| 284 |
+
|
| 285 |
+
def forward(self, x: Tensor) -> Tensor:
|
| 286 |
+
return self.ffn(self.norm(x))
|
| 287 |
+
|
| 288 |
+
|
| 289 |
+
class MSAEncoderBlock(nn.Module):
|
| 290 |
+
"""One experimental MSA update block."""
|
| 291 |
+
|
| 292 |
+
def __init__(
|
| 293 |
+
self,
|
| 294 |
+
d_msa: int,
|
| 295 |
+
d_pair: int,
|
| 296 |
+
d_hidden: int = 32,
|
| 297 |
+
n_heads_msa: int = 8,
|
| 298 |
+
msa_head_width: int = 32,
|
| 299 |
+
) -> None:
|
| 300 |
+
super().__init__()
|
| 301 |
+
self.outer_product_mean = OuterProductMean(
|
| 302 |
+
d_msa, d_hidden, d_pair, divide_outer_before_proj=True
|
| 303 |
+
)
|
| 304 |
+
self.msa_pair_weighted_averaging = MSAPairWeightedAveraging(
|
| 305 |
+
d_msa, d_pair, n_heads_msa, msa_head_width
|
| 306 |
+
)
|
| 307 |
+
self.msa_transition = _TransitionFFN(d_msa, expansion_ratio=4)
|
| 308 |
+
self.tri_mul_out = TriangleMultiplicativeUpdate(dim=d_pair, _outgoing=True)
|
| 309 |
+
self.tri_mul_in = TriangleMultiplicativeUpdate(dim=d_pair, _outgoing=False)
|
| 310 |
+
self.pair_transition = _TransitionFFN(d_pair, expansion_ratio=4)
|
| 311 |
+
|
| 312 |
+
def set_chunk_size(self, chunk_size: int | None) -> None:
|
| 313 |
+
self.outer_product_mean.set_chunk_size(chunk_size)
|
| 314 |
+
self.tri_mul_out.set_chunk_size(chunk_size)
|
| 315 |
+
self.tri_mul_in.set_chunk_size(chunk_size)
|
| 316 |
+
|
| 317 |
+
def forward(
|
| 318 |
+
self,
|
| 319 |
+
msa_repr: Tensor,
|
| 320 |
+
pair_repr: Tensor,
|
| 321 |
+
msa_attention_mask: Tensor,
|
| 322 |
+
pair_attention_mask: Tensor,
|
| 323 |
+
msa_track_mask: Tensor | None = None,
|
| 324 |
+
) -> tuple[Tensor, Tensor]:
|
| 325 |
+
mask4d = (
|
| 326 |
+
msa_track_mask[:, None, None, None].to(dtype=msa_repr.dtype)
|
| 327 |
+
if msa_track_mask is not None
|
| 328 |
+
else None
|
| 329 |
+
)
|
| 330 |
+
|
| 331 |
+
pair_mask4d = mask4d[:, :, :1] if mask4d is not None else None
|
| 332 |
+
|
| 333 |
+
msa_update = self.msa_pair_weighted_averaging(
|
| 334 |
+
msa_repr, pair_repr, pair_attention_mask
|
| 335 |
+
)
|
| 336 |
+
if mask4d is not None:
|
| 337 |
+
msa_update = msa_update * mask4d
|
| 338 |
+
msa_repr = msa_repr + msa_update
|
| 339 |
+
|
| 340 |
+
msa_transition = self.msa_transition(msa_repr)
|
| 341 |
+
if mask4d is not None:
|
| 342 |
+
msa_transition = msa_transition * mask4d
|
| 343 |
+
msa_repr = msa_repr + msa_transition
|
| 344 |
+
|
| 345 |
+
pair_opm = self.outer_product_mean(msa_repr, msa_attention_mask)
|
| 346 |
+
if pair_mask4d is not None:
|
| 347 |
+
pair_opm = pair_opm * pair_mask4d
|
| 348 |
+
pair_repr = pair_repr + pair_opm
|
| 349 |
+
|
| 350 |
+
pair_out = self.tri_mul_out(pair_repr, mask=pair_attention_mask)
|
| 351 |
+
if pair_mask4d is not None:
|
| 352 |
+
pair_out = pair_out * pair_mask4d
|
| 353 |
+
pair_repr = pair_repr + pair_out
|
| 354 |
+
|
| 355 |
+
pair_in = self.tri_mul_in(pair_repr, mask=pair_attention_mask)
|
| 356 |
+
if pair_mask4d is not None:
|
| 357 |
+
pair_in = pair_in * pair_mask4d
|
| 358 |
+
pair_repr = pair_repr + pair_in
|
| 359 |
+
|
| 360 |
+
pair_transition = self.pair_transition(pair_repr)
|
| 361 |
+
if pair_mask4d is not None:
|
| 362 |
+
pair_transition = pair_transition * pair_mask4d
|
| 363 |
+
pair_repr = pair_repr + pair_transition
|
| 364 |
+
return msa_repr, pair_repr
|
| 365 |
+
|
| 366 |
+
|
| 367 |
+
class MSAEncoder(nn.Module):
|
| 368 |
+
def __init__(
|
| 369 |
+
self,
|
| 370 |
+
d_msa: int,
|
| 371 |
+
d_pair: int,
|
| 372 |
+
d_inputs: int,
|
| 373 |
+
d_hidden: int = 32,
|
| 374 |
+
n_layers: int = 4,
|
| 375 |
+
n_heads_msa: int = 8,
|
| 376 |
+
msa_head_width: int = 32,
|
| 377 |
+
) -> None:
|
| 378 |
+
super().__init__()
|
| 379 |
+
self.embed = nn.Linear(35, d_msa, bias=False)
|
| 380 |
+
self.project_inputs = nn.Linear(d_inputs, d_msa, bias=False)
|
| 381 |
+
self.blocks = nn.ModuleList(
|
| 382 |
+
[
|
| 383 |
+
MSAEncoderBlock(
|
| 384 |
+
d_msa=d_msa,
|
| 385 |
+
d_pair=d_pair,
|
| 386 |
+
d_hidden=d_hidden,
|
| 387 |
+
n_heads_msa=n_heads_msa,
|
| 388 |
+
msa_head_width=msa_head_width,
|
| 389 |
+
)
|
| 390 |
+
for _ in range(n_layers)
|
| 391 |
+
]
|
| 392 |
+
)
|
| 393 |
+
|
| 394 |
+
def set_chunk_size(self, chunk_size: int | None) -> None:
|
| 395 |
+
for block in self.blocks:
|
| 396 |
+
cast(MSAEncoderBlock, block).set_chunk_size(chunk_size)
|
| 397 |
+
|
| 398 |
+
def forward(
|
| 399 |
+
self,
|
| 400 |
+
x_pair: Tensor,
|
| 401 |
+
x_inputs: Tensor,
|
| 402 |
+
msa_oh: Tensor,
|
| 403 |
+
has_deletion: Tensor,
|
| 404 |
+
deletion_value: Tensor,
|
| 405 |
+
msa_attention_mask: Tensor,
|
| 406 |
+
) -> Tensor:
|
| 407 |
+
batch_size, _, depth = msa_attention_mask.shape
|
| 408 |
+
m_feat = torch.cat(
|
| 409 |
+
[msa_oh, has_deletion.unsqueeze(-1), deletion_value.unsqueeze(-1)],
|
| 410 |
+
dim=-1,
|
| 411 |
+
)
|
| 412 |
+
m = self.embed(m_feat) + self.project_inputs(x_inputs).unsqueeze(2)
|
| 413 |
+
if depth > 1:
|
| 414 |
+
msa_track_mask = msa_attention_mask[:, :, 1:].any(dim=(1, 2))
|
| 415 |
+
else:
|
| 416 |
+
msa_track_mask = torch.zeros(
|
| 417 |
+
batch_size, dtype=torch.bool, device=x_pair.device
|
| 418 |
+
)
|
| 419 |
+
tok_mask = msa_attention_mask[:, :, 0]
|
| 420 |
+
pair_attention_mask = tok_mask.unsqueeze(2) * tok_mask.unsqueeze(1)
|
| 421 |
+
for block in self.blocks:
|
| 422 |
+
m, x_pair = cast(MSAEncoderBlock, block)(
|
| 423 |
+
m,
|
| 424 |
+
x_pair,
|
| 425 |
+
msa_attention_mask,
|
| 426 |
+
pair_attention_mask,
|
| 427 |
+
msa_track_mask,
|
| 428 |
+
)
|
| 429 |
+
return x_pair * msa_track_mask[:, None, None, None].to(dtype=x_pair.dtype)
|
| 430 |
+
|
| 431 |
+
|
| 432 |
+
class ESMFold2ExperimentalModel(PreTrainedModel):
|
| 433 |
+
"""Experimental ESMFold2 architecture used by binder-design checkpoints."""
|
| 434 |
+
|
| 435 |
+
config_class = ESMFold2Config
|
| 436 |
+
_keys_to_ignore_on_load_unexpected = [r"\._extra_state$"]
|
| 437 |
+
|
| 438 |
+
def __init__(self, config: ESMFold2Config) -> None:
|
| 439 |
+
super().__init__(config)
|
| 440 |
+
d_inputs = config.inputs.d_inputs
|
| 441 |
+
d_pair = config.d_pair
|
| 442 |
+
|
| 443 |
+
self.inputs_embedder = InputsEmbedder(config)
|
| 444 |
+
self.z_init_1 = nn.Linear(d_inputs, d_pair, bias=False)
|
| 445 |
+
self.z_init_2 = nn.Linear(d_inputs, d_pair, bias=False)
|
| 446 |
+
self.rel_pos = ResIdxAsymIdSymIdEntityIdEncoding(
|
| 447 |
+
n_relative_residx_bins=config.n_relative_residx_bins,
|
| 448 |
+
n_relative_chain_bins=config.n_relative_chain_bins,
|
| 449 |
+
d_pair=d_pair,
|
| 450 |
+
)
|
| 451 |
+
self.token_bonds = nn.Linear(1, d_pair, bias=False)
|
| 452 |
+
self.language_model = LanguageModelShim(
|
| 453 |
+
d_z=d_pair, d_model=config.lm_d_model, num_layers=config.lm_num_layers
|
| 454 |
+
)
|
| 455 |
+
self._esmc: nn.Module | None = None
|
| 456 |
+
self._esmc_fp8 = False
|
| 457 |
+
self._esmfold2_input_builder: Any | None = None
|
| 458 |
+
|
| 459 |
+
pf = config.folding_trunk
|
| 460 |
+
self.folding_trunk = FoldingTrunk(
|
| 461 |
+
n_layers=pf.n_layers, d_pair=d_pair, expansion_ratio=4
|
| 462 |
+
)
|
| 463 |
+
self.pair_loop_proj = nn.Sequential(
|
| 464 |
+
nn.LayerNorm(d_pair), nn.Linear(d_pair, d_pair, bias=False)
|
| 465 |
+
)
|
| 466 |
+
nn.init.zeros_(cast(nn.Linear, self.pair_loop_proj[1]).weight)
|
| 467 |
+
|
| 468 |
+
self.structure_head = DiffusionStructureHead(config)
|
| 469 |
+
self.distogram_head = nn.Linear(
|
| 470 |
+
d_pair, config.structure_head.distogram_bins, bias=True
|
| 471 |
+
)
|
| 472 |
+
self.confidence_head: ConfidenceHead | None = (
|
| 473 |
+
ConfidenceHead(config) if config.confidence_head.enabled else None
|
| 474 |
+
)
|
| 475 |
+
|
| 476 |
+
msa_cfg = config.msa_encoder
|
| 477 |
+
self.msa_encoder: MSAEncoder | None = None
|
| 478 |
+
if msa_cfg.enabled:
|
| 479 |
+
self.msa_encoder = MSAEncoder(
|
| 480 |
+
d_msa=msa_cfg.d_msa,
|
| 481 |
+
d_pair=d_pair,
|
| 482 |
+
d_inputs=d_inputs,
|
| 483 |
+
d_hidden=msa_cfg.d_hidden,
|
| 484 |
+
n_layers=msa_cfg.n_layers,
|
| 485 |
+
n_heads_msa=msa_cfg.n_heads_msa,
|
| 486 |
+
msa_head_width=msa_cfg.msa_head_width,
|
| 487 |
+
)
|
| 488 |
+
|
| 489 |
+
self.post_init()
|
| 490 |
+
|
| 491 |
+
@property
|
| 492 |
+
def device(self) -> torch.device:
|
| 493 |
+
return next(self.parameters()).device
|
| 494 |
+
|
| 495 |
+
def set_kernel_backend(self, backend: str | None) -> None:
|
| 496 |
+
self.folding_trunk.set_kernel_backend(backend)
|
| 497 |
+
if self.confidence_head is not None:
|
| 498 |
+
self.confidence_head.set_kernel_backend(backend)
|
| 499 |
+
self.structure_head.set_kernel_backend(backend)
|
| 500 |
+
|
| 501 |
+
def set_chunk_size(self, chunk_size: int | None) -> None:
|
| 502 |
+
self.folding_trunk.set_chunk_size(chunk_size)
|
| 503 |
+
if self.confidence_head is not None:
|
| 504 |
+
self.confidence_head.set_chunk_size(chunk_size)
|
| 505 |
+
if self.msa_encoder is not None:
|
| 506 |
+
self.msa_encoder.set_chunk_size(chunk_size)
|
| 507 |
+
|
| 508 |
+
def configure_lm_dropout(
|
| 509 |
+
self,
|
| 510 |
+
lm_dropout: float,
|
| 511 |
+
*,
|
| 512 |
+
force_lm_dropout_during_inference: bool = True,
|
| 513 |
+
) -> None:
|
| 514 |
+
self.config.lm_dropout = lm_dropout
|
| 515 |
+
self.config.force_lm_dropout_during_inference = (
|
| 516 |
+
force_lm_dropout_during_inference
|
| 517 |
+
)
|
| 518 |
+
|
| 519 |
+
def load_esmc(self, esmc_model_path: str, precision: str = "bf16") -> None:
|
| 520 |
+
dtype_map = {
|
| 521 |
+
"bf16": torch.bfloat16,
|
| 522 |
+
"fp32": torch.float32,
|
| 523 |
+
}
|
| 524 |
+
if precision not in dtype_map:
|
| 525 |
+
if precision == "fp8":
|
| 526 |
+
raise RuntimeError(
|
| 527 |
+
"esmc_precision='fp8' is supported only by the standard "
|
| 528 |
+
"released ESMFold2 model. The experimental binder-design "
|
| 529 |
+
"model keeps the FastPLMs ESM++ backbone in bf16 or fp32."
|
| 530 |
+
)
|
| 531 |
+
raise ValueError(f"precision must be one of {list(dtype_map)}, got {precision!r}")
|
| 532 |
+
esmc = _load_fastplms_esmplusplus_for_esmfold2(
|
| 533 |
+
esmc_model_path=esmc_model_path,
|
| 534 |
+
attn_backend=self.config.esmc_attn_backend,
|
| 535 |
+
device=self.device,
|
| 536 |
+
dtype=dtype_map[precision],
|
| 537 |
+
)
|
| 538 |
+
assert esmc.config.hidden_size == self.config.lm_d_model, (
|
| 539 |
+
f"ESMFold2 expected lm_d_model={self.config.lm_d_model}, "
|
| 540 |
+
f"but loaded ESM++ hidden_size={esmc.config.hidden_size}."
|
| 541 |
+
)
|
| 542 |
+
assert esmc.config.num_hidden_layers == self.config.lm_num_layers, (
|
| 543 |
+
f"ESMFold2 expected lm_num_layers={self.config.lm_num_layers}, "
|
| 544 |
+
f"but loaded ESM++ num_hidden_layers={esmc.config.num_hidden_layers}."
|
| 545 |
+
)
|
| 546 |
+
for parameter in esmc.parameters():
|
| 547 |
+
parameter.requires_grad_(False)
|
| 548 |
+
self._esmc_fp8 = False
|
| 549 |
+
self._esmc = esmc
|
| 550 |
+
|
| 551 |
+
@classmethod
|
| 552 |
+
def from_pretrained(
|
| 553 |
+
cls,
|
| 554 |
+
pretrained_model_name_or_path,
|
| 555 |
+
*model_args,
|
| 556 |
+
load_esmc: bool = True,
|
| 557 |
+
**kwargs,
|
| 558 |
+
):
|
| 559 |
+
if "config" not in kwargs:
|
| 560 |
+
kwargs["config"] = ESMFold2Config.from_pretrained(
|
| 561 |
+
pretrained_model_name_or_path, **kwargs
|
| 562 |
+
)
|
| 563 |
+
esmc_precision = kwargs.pop("esmc_precision", "bf16")
|
| 564 |
+
model = super().from_pretrained(pretrained_model_name_or_path, *model_args, **kwargs)
|
| 565 |
+
if load_esmc:
|
| 566 |
+
model.load_esmc(model.config.esmc_id, precision=esmc_precision)
|
| 567 |
+
return model
|
| 568 |
+
|
| 569 |
+
def apply_torch_compile(
|
| 570 |
+
self, mode: str = "fixed_seqlen", dynamic: bool | None = None
|
| 571 |
+
) -> None:
|
| 572 |
+
import torch._dynamo
|
| 573 |
+
|
| 574 |
+
torch._dynamo.config.cache_size_limit = 512
|
| 575 |
+
torch._dynamo.config.accumulated_cache_size_limit = 512
|
| 576 |
+
torch._dynamo.config.capture_scalar_outputs = True
|
| 577 |
+
|
| 578 |
+
if dynamic is None:
|
| 579 |
+
dynamic = mode == "dynamic_seqlen"
|
| 580 |
+
compile_kwargs: dict[str, bool] = {"dynamic": dynamic}
|
| 581 |
+
compile_targets = (
|
| 582 |
+
PairUpdateBlock,
|
| 583 |
+
DiffusionTransformer,
|
| 584 |
+
DiffusionModule,
|
| 585 |
+
MSAEncoderBlock,
|
| 586 |
+
)
|
| 587 |
+
|
| 588 |
+
def _maybe_compile(module: nn.Module) -> None:
|
| 589 |
+
if isinstance(module, compile_targets):
|
| 590 |
+
module.forward = torch.compile(module.forward, **compile_kwargs)
|
| 591 |
+
|
| 592 |
+
self.apply(_maybe_compile)
|
| 593 |
+
|
| 594 |
+
def _compute_lm_hidden_states(
|
| 595 |
+
self,
|
| 596 |
+
input_ids: Tensor,
|
| 597 |
+
asym_id: Tensor,
|
| 598 |
+
residue_index: Tensor,
|
| 599 |
+
mol_type: Tensor,
|
| 600 |
+
tok_mask: Tensor,
|
| 601 |
+
) -> Tensor:
|
| 602 |
+
assert self._esmc is not None
|
| 603 |
+
pad_to = 8 if self._esmc_fp8 else None
|
| 604 |
+
with _lm_precision_context(self._esmc_fp8):
|
| 605 |
+
return compute_lm_hidden_states(
|
| 606 |
+
self._esmc,
|
| 607 |
+
input_ids,
|
| 608 |
+
asym_id,
|
| 609 |
+
residue_index,
|
| 610 |
+
mol_type,
|
| 611 |
+
tok_mask,
|
| 612 |
+
pad_to_multiple=pad_to,
|
| 613 |
+
)
|
| 614 |
+
|
| 615 |
+
def forward(
|
| 616 |
+
self,
|
| 617 |
+
token_index: Tensor,
|
| 618 |
+
residue_index: Tensor,
|
| 619 |
+
asym_id: Tensor,
|
| 620 |
+
sym_id: Tensor,
|
| 621 |
+
entity_id: Tensor,
|
| 622 |
+
mol_type: Tensor,
|
| 623 |
+
res_type: Tensor,
|
| 624 |
+
token_bonds: Tensor,
|
| 625 |
+
token_attention_mask: Tensor,
|
| 626 |
+
ref_pos: Tensor,
|
| 627 |
+
ref_element: Tensor,
|
| 628 |
+
ref_charge: Tensor,
|
| 629 |
+
ref_atom_name_chars: Tensor,
|
| 630 |
+
ref_space_uid: Tensor,
|
| 631 |
+
atom_attention_mask: Tensor,
|
| 632 |
+
atom_to_token: Tensor,
|
| 633 |
+
distogram_atom_idx: Tensor,
|
| 634 |
+
deletion_mean: Tensor | None = None,
|
| 635 |
+
msa: Tensor | None = None,
|
| 636 |
+
has_deletion: Tensor | None = None,
|
| 637 |
+
deletion_value: Tensor | None = None,
|
| 638 |
+
msa_attention_mask: Tensor | None = None,
|
| 639 |
+
input_ids: Tensor | None = None,
|
| 640 |
+
lm_hidden_states: Tensor | None = None,
|
| 641 |
+
res_type_soft: Tensor | None = None,
|
| 642 |
+
num_loops: int | None = None,
|
| 643 |
+
num_diffusion_samples: int | None = None,
|
| 644 |
+
num_sampling_steps: int | None = None,
|
| 645 |
+
early_exit: bool = False,
|
| 646 |
+
seed: int | None = None,
|
| 647 |
+
calculate_confidence: bool = True,
|
| 648 |
+
provide_soft_sequence_to_msa_and_profile: bool = True,
|
| 649 |
+
noise_scale: float | None = None,
|
| 650 |
+
step_scale: float | None = None,
|
| 651 |
+
max_inference_sigma: int | None = None,
|
| 652 |
+
) -> dict[str, Tensor]:
|
| 653 |
+
del noise_scale, step_scale, max_inference_sigma
|
| 654 |
+
tok_mask = token_attention_mask
|
| 655 |
+
atm_mask = atom_attention_mask
|
| 656 |
+
n_loops = num_loops if num_loops is not None else self.config.num_loops
|
| 657 |
+
n_samples = (
|
| 658 |
+
num_diffusion_samples
|
| 659 |
+
if num_diffusion_samples is not None
|
| 660 |
+
else self.config.num_diffusion_samples
|
| 661 |
+
)
|
| 662 |
+
|
| 663 |
+
if res_type.dim() == 2:
|
| 664 |
+
res_type_oh = F.one_hot(res_type.long(), num_classes=NUM_RES_TYPES).float()
|
| 665 |
+
res_type_oh = res_type_oh * tok_mask.unsqueeze(-1).float()
|
| 666 |
+
else:
|
| 667 |
+
res_type_oh = res_type.float()
|
| 668 |
+
|
| 669 |
+
if msa is not None:
|
| 670 |
+
msa_oh_profile = F.one_hot(msa.long(), num_classes=NUM_RES_TYPES).float()
|
| 671 |
+
if msa_attention_mask is not None:
|
| 672 |
+
mask_f = msa_attention_mask.float().unsqueeze(-1)
|
| 673 |
+
msa_oh_profile = msa_oh_profile * mask_f
|
| 674 |
+
valid_seq_count = msa_attention_mask.float().sum(dim=1).clamp(min=1)
|
| 675 |
+
profile = msa_oh_profile.sum(dim=1) / valid_seq_count.unsqueeze(-1)
|
| 676 |
+
else:
|
| 677 |
+
profile = msa_oh_profile.mean(dim=1)
|
| 678 |
+
else:
|
| 679 |
+
profile = res_type_oh
|
| 680 |
+
|
| 681 |
+
if res_type_soft is not None:
|
| 682 |
+
res_type_oh = res_type_soft.float()
|
| 683 |
+
if (
|
| 684 |
+
not self.config.disable_msa_features
|
| 685 |
+
and provide_soft_sequence_to_msa_and_profile
|
| 686 |
+
):
|
| 687 |
+
profile = res_type_oh
|
| 688 |
+
msa = res_type_oh.unsqueeze(1)
|
| 689 |
+
msa_attention_mask = tok_mask.unsqueeze(1)
|
| 690 |
+
|
| 691 |
+
if deletion_mean is None:
|
| 692 |
+
deletion_mean = torch.zeros(
|
| 693 |
+
res_type.shape[0], res_type.shape[1], device=res_type.device
|
| 694 |
+
)
|
| 695 |
+
if self.config.disable_msa_features:
|
| 696 |
+
profile = torch.zeros_like(profile)
|
| 697 |
+
deletion_mean = torch.zeros_like(deletion_mean)
|
| 698 |
+
|
| 699 |
+
ref_element_oh = F.one_hot(
|
| 700 |
+
ref_element.long(), num_classes=MAX_ATOMIC_NUMBER
|
| 701 |
+
).float()
|
| 702 |
+
ref_atom_name_chars_oh = F.one_hot(
|
| 703 |
+
ref_atom_name_chars.long(), num_classes=CHAR_VOCAB_SIZE
|
| 704 |
+
).float()
|
| 705 |
+
atm_mask_f = atm_mask.float()
|
| 706 |
+
ref_element_oh = ref_element_oh * atm_mask_f.unsqueeze(-1)
|
| 707 |
+
ref_atom_name_chars_oh = ref_atom_name_chars_oh * atm_mask_f.unsqueeze(
|
| 708 |
+
-1
|
| 709 |
+
).unsqueeze(-1)
|
| 710 |
+
atom_to_token = atom_to_token * atm_mask.long()
|
| 711 |
+
|
| 712 |
+
use_amp = ref_pos.device.type == "cuda"
|
| 713 |
+
with (
|
| 714 |
+
torch.set_grad_enabled(res_type_soft is not None),
|
| 715 |
+
torch.amp.autocast("cuda", enabled=use_amp, dtype=torch.bfloat16),
|
| 716 |
+
):
|
| 717 |
+
x_inputs = self.inputs_embedder(
|
| 718 |
+
aatype=res_type_oh,
|
| 719 |
+
profile=profile.float(),
|
| 720 |
+
deletion_mean=deletion_mean.float(),
|
| 721 |
+
ref_pos=ref_pos,
|
| 722 |
+
atom_attention_mask=atm_mask,
|
| 723 |
+
ref_space_uid=ref_space_uid,
|
| 724 |
+
ref_charge=ref_charge,
|
| 725 |
+
ref_element=ref_element_oh,
|
| 726 |
+
ref_atom_name_chars=ref_atom_name_chars_oh,
|
| 727 |
+
atom_to_token=atom_to_token,
|
| 728 |
+
)
|
| 729 |
+
|
| 730 |
+
z_init = self.z_init_1(x_inputs).unsqueeze(2) + self.z_init_2(
|
| 731 |
+
x_inputs
|
| 732 |
+
).unsqueeze(1)
|
| 733 |
+
relative_position_encoding = self.rel_pos(
|
| 734 |
+
residue_index=residue_index,
|
| 735 |
+
asym_id=asym_id,
|
| 736 |
+
sym_id=sym_id,
|
| 737 |
+
entity_id=entity_id,
|
| 738 |
+
token_index=token_index,
|
| 739 |
+
)
|
| 740 |
+
token_bonds_encoding = self.token_bonds(token_bonds.float())
|
| 741 |
+
z_init = z_init + relative_position_encoding + token_bonds_encoding
|
| 742 |
+
|
| 743 |
+
if (
|
| 744 |
+
lm_hidden_states is None
|
| 745 |
+
and input_ids is not None
|
| 746 |
+
and self._esmc is not None
|
| 747 |
+
):
|
| 748 |
+
lm_hidden_states = self._compute_lm_hidden_states(
|
| 749 |
+
input_ids, asym_id, residue_index, mol_type, tok_mask
|
| 750 |
+
)
|
| 751 |
+
if lm_hidden_states is not None:
|
| 752 |
+
lm_dropout = (
|
| 753 |
+
self.config.lm_dropout
|
| 754 |
+
if self.config.force_lm_dropout_during_inference or self.training
|
| 755 |
+
else 0.0
|
| 756 |
+
)
|
| 757 |
+
lm_z = self.language_model(
|
| 758 |
+
lm_hidden_states.detach(), lm_dropout=lm_dropout
|
| 759 |
+
)
|
| 760 |
+
z_init = z_init + lm_z.to(z_init.dtype)
|
| 761 |
+
|
| 762 |
+
msa_kwargs: dict[str, Tensor] | None = None
|
| 763 |
+
if self.msa_encoder is not None and msa is not None:
|
| 764 |
+
if msa.dim() == 4:
|
| 765 |
+
batch_msa, depth, length_msa, _ = msa.shape
|
| 766 |
+
msa_oh = msa.permute(0, 2, 1, 3).float()
|
| 767 |
+
else:
|
| 768 |
+
batch_msa, depth, length_msa = msa.shape
|
| 769 |
+
msa_oh = F.one_hot(
|
| 770 |
+
msa.permute(0, 2, 1).long(), num_classes=NUM_RES_TYPES
|
| 771 |
+
).float()
|
| 772 |
+
msa_attn = (
|
| 773 |
+
msa_attention_mask.permute(0, 2, 1).float()
|
| 774 |
+
if msa_attention_mask is not None
|
| 775 |
+
else tok_mask[:, :, None].expand(-1, -1, depth).float()
|
| 776 |
+
)
|
| 777 |
+
msa_oh = msa_oh * msa_attn.unsqueeze(-1)
|
| 778 |
+
hd = (
|
| 779 |
+
has_deletion.permute(0, 2, 1).float()
|
| 780 |
+
if has_deletion is not None
|
| 781 |
+
else torch.zeros(batch_msa, length_msa, depth, device=msa.device)
|
| 782 |
+
)
|
| 783 |
+
dv = (
|
| 784 |
+
deletion_value.permute(0, 2, 1).float()
|
| 785 |
+
if deletion_value is not None
|
| 786 |
+
else torch.zeros(batch_msa, length_msa, depth, device=msa.device)
|
| 787 |
+
)
|
| 788 |
+
msa_kwargs = {
|
| 789 |
+
"x_inputs": x_inputs,
|
| 790 |
+
"msa_oh": msa_oh,
|
| 791 |
+
"has_deletion": hd,
|
| 792 |
+
"deletion_value": dv,
|
| 793 |
+
"msa_attention_mask": msa_attn,
|
| 794 |
+
}
|
| 795 |
+
|
| 796 |
+
pair_mask = tok_mask[:, :, None].float() * tok_mask[:, None, :].float()
|
| 797 |
+
z = torch.zeros_like(z_init)
|
| 798 |
+
prev_pair: Tensor | None = None
|
| 799 |
+
prev_disto_probs: Tensor | None = None
|
| 800 |
+
for loop_num in range(n_loops + 1):
|
| 801 |
+
z = z_init + self.pair_loop_proj(z)
|
| 802 |
+
if msa_kwargs is not None and self.msa_encoder is not None:
|
| 803 |
+
z = z + self.msa_encoder(x_pair=z, **msa_kwargs).to(z.dtype)
|
| 804 |
+
z = self.folding_trunk(z, pair_attention_mask=pair_mask)
|
| 805 |
+
|
| 806 |
+
if early_exit and loop_num < n_loops:
|
| 807 |
+
l2_converged = False
|
| 808 |
+
if prev_pair is not None and loop_num > 0:
|
| 809 |
+
rel_l2 = (z.float() - prev_pair.float()).norm() / prev_pair.float().norm().clamp(
|
| 810 |
+
min=1e-8
|
| 811 |
+
)
|
| 812 |
+
l2_converged = rel_l2.item() < 0.25
|
| 813 |
+
prev_pair = z.detach().clone()
|
| 814 |
+
sym_z = z.float() + z.float().transpose(-2, -3)
|
| 815 |
+
cur_probs = F.softmax(self.distogram_head(sym_z).float(), dim=-1)
|
| 816 |
+
if prev_disto_probs is not None and loop_num > 0:
|
| 817 |
+
kl_per_pair = (
|
| 818 |
+
cur_probs
|
| 819 |
+
* (
|
| 820 |
+
cur_probs.clamp(min=1e-8)
|
| 821 |
+
/ prev_disto_probs.clamp(min=1e-8)
|
| 822 |
+
).log()
|
| 823 |
+
).sum(-1)
|
| 824 |
+
kl = (kl_per_pair + kl_per_pair.transpose(-1, -2)).mean() / 2
|
| 825 |
+
if l2_converged or kl.item() < 0.05:
|
| 826 |
+
break
|
| 827 |
+
prev_disto_probs = cur_probs.detach()
|
| 828 |
+
|
| 829 |
+
distogram_logits = self.distogram_head(z + z.transpose(-2, -3))
|
| 830 |
+
|
| 831 |
+
with torch.no_grad(), _seed_context(seed):
|
| 832 |
+
structure_output = self.structure_head.sample(
|
| 833 |
+
z_trunk=z.float(),
|
| 834 |
+
s_inputs=x_inputs,
|
| 835 |
+
s_trunk=None,
|
| 836 |
+
relative_position_encoding=relative_position_encoding,
|
| 837 |
+
ref_pos=ref_pos,
|
| 838 |
+
ref_charge=ref_charge,
|
| 839 |
+
ref_mask=atm_mask,
|
| 840 |
+
ref_element=ref_element_oh,
|
| 841 |
+
ref_atom_name_chars=ref_atom_name_chars_oh,
|
| 842 |
+
ref_space_uid=ref_space_uid,
|
| 843 |
+
tok_idx=atom_to_token,
|
| 844 |
+
asym_id=asym_id,
|
| 845 |
+
residue_index=residue_index,
|
| 846 |
+
entity_id=entity_id,
|
| 847 |
+
token_index=token_index,
|
| 848 |
+
sym_id=sym_id,
|
| 849 |
+
token_attention_mask=tok_mask,
|
| 850 |
+
num_diffusion_samples=n_samples,
|
| 851 |
+
num_sampling_steps=num_sampling_steps,
|
| 852 |
+
return_atom_repr=False,
|
| 853 |
+
denoising_early_exit_rmsd=(0.10 if early_exit else None),
|
| 854 |
+
)
|
| 855 |
+
sample_coords = structure_output["sample_atom_coords"]
|
| 856 |
+
assert sample_coords is not None
|
| 857 |
+
|
| 858 |
+
output: dict[str, Tensor] = {
|
| 859 |
+
"distogram_logits": distogram_logits,
|
| 860 |
+
"sample_atom_coords": sample_coords,
|
| 861 |
+
}
|
| 862 |
+
if calculate_confidence and self.confidence_head is not None:
|
| 863 |
+
confidence_output = self.confidence_head(
|
| 864 |
+
s_inputs=x_inputs.detach(),
|
| 865 |
+
z=z.detach().float(),
|
| 866 |
+
x_pred=sample_coords.detach(),
|
| 867 |
+
distogram_atom_idx=distogram_atom_idx,
|
| 868 |
+
token_attention_mask=tok_mask,
|
| 869 |
+
atom_to_token=atom_to_token,
|
| 870 |
+
atom_attention_mask=atm_mask,
|
| 871 |
+
asym_id=asym_id,
|
| 872 |
+
mol_type=mol_type,
|
| 873 |
+
num_diffusion_samples=n_samples,
|
| 874 |
+
relative_position_encoding=relative_position_encoding.detach(),
|
| 875 |
+
token_bonds_encoding=token_bonds_encoding.detach(),
|
| 876 |
+
)
|
| 877 |
+
output.update(confidence_output)
|
| 878 |
+
output["atom_pad_mask"] = (
|
| 879 |
+
atm_mask.unsqueeze(0) if atm_mask.dim() == 1 else atm_mask
|
| 880 |
+
)
|
| 881 |
+
output["residue_index"] = residue_index
|
| 882 |
+
output["entity_id"] = entity_id
|
| 883 |
+
return output
|
| 884 |
+
|
| 885 |
+
@property
|
| 886 |
+
def input_builder(self):
|
| 887 |
+
if self._esmfold2_input_builder is None:
|
| 888 |
+
from .esmfold2_processor import ESMFold2InputBuilder
|
| 889 |
+
|
| 890 |
+
self._esmfold2_input_builder = ESMFold2InputBuilder()
|
| 891 |
+
return self._esmfold2_input_builder
|
| 892 |
+
|
| 893 |
+
@property
|
| 894 |
+
def input_types(self):
|
| 895 |
+
from . import esmfold2_types
|
| 896 |
+
|
| 897 |
+
return esmfold2_types
|
| 898 |
+
|
| 899 |
+
def prepare_structure_input(self, input, seed: int | None = None):
|
| 900 |
+
return self.input_builder.prepare_input(input, seed=seed, device=self.device)
|
| 901 |
+
|
| 902 |
+
@torch.no_grad()
|
| 903 |
+
def infer_protein(self, seq: str, **forward_kwargs) -> dict[str, Tensor]:
|
| 904 |
+
from .protein_utils import prepare_protein_features
|
| 905 |
+
|
| 906 |
+
features = prepare_protein_features(seq)
|
| 907 |
+
features = {name: tensor.to(self.device) for name, tensor in features.items()}
|
| 908 |
+
output = self(**features, **forward_kwargs)
|
| 909 |
+
for name in (
|
| 910 |
+
"res_type",
|
| 911 |
+
"atom_to_token",
|
| 912 |
+
"ref_atom_name_chars",
|
| 913 |
+
"atom_attention_mask",
|
| 914 |
+
"token_attention_mask",
|
| 915 |
+
"residue_index",
|
| 916 |
+
):
|
| 917 |
+
output[name] = features[name]
|
| 918 |
+
return output
|
| 919 |
+
|
| 920 |
+
def fold(
|
| 921 |
+
self,
|
| 922 |
+
input,
|
| 923 |
+
*,
|
| 924 |
+
num_loops: int = 3,
|
| 925 |
+
num_sampling_steps: int = 50,
|
| 926 |
+
num_diffusion_samples: int = 1,
|
| 927 |
+
seed: int | None = None,
|
| 928 |
+
noise_scale: float | None = None,
|
| 929 |
+
step_scale: float | None = None,
|
| 930 |
+
max_inference_sigma: int | None = None,
|
| 931 |
+
early_exit: bool = False,
|
| 932 |
+
complex_id: str = "pred",
|
| 933 |
+
):
|
| 934 |
+
return self.input_builder.fold(
|
| 935 |
+
self,
|
| 936 |
+
input,
|
| 937 |
+
num_loops=num_loops,
|
| 938 |
+
num_sampling_steps=num_sampling_steps,
|
| 939 |
+
num_diffusion_samples=num_diffusion_samples,
|
| 940 |
+
seed=seed,
|
| 941 |
+
noise_scale=noise_scale,
|
| 942 |
+
step_scale=step_scale,
|
| 943 |
+
max_inference_sigma=max_inference_sigma,
|
| 944 |
+
early_exit=early_exit,
|
| 945 |
+
complex_id=complex_id,
|
| 946 |
+
)
|
| 947 |
+
|
| 948 |
+
def fold_protein(
|
| 949 |
+
self,
|
| 950 |
+
sequence: str,
|
| 951 |
+
*,
|
| 952 |
+
chain_id: str = "A",
|
| 953 |
+
num_loops: int = 3,
|
| 954 |
+
num_sampling_steps: int = 50,
|
| 955 |
+
num_diffusion_samples: int = 1,
|
| 956 |
+
seed: int | None = None,
|
| 957 |
+
complex_id: str = "pred",
|
| 958 |
+
):
|
| 959 |
+
from .esmfold2_types import ProteinInput, StructurePredictionInput
|
| 960 |
+
|
| 961 |
+
input = StructurePredictionInput(
|
| 962 |
+
sequences=[ProteinInput(id=chain_id, sequence=sequence)]
|
| 963 |
+
)
|
| 964 |
+
return self.fold(
|
| 965 |
+
input,
|
| 966 |
+
num_loops=num_loops,
|
| 967 |
+
num_sampling_steps=num_sampling_steps,
|
| 968 |
+
num_diffusion_samples=num_diffusion_samples,
|
| 969 |
+
seed=seed,
|
| 970 |
+
complex_id=complex_id,
|
| 971 |
+
)
|
| 972 |
+
|
| 973 |
+
@staticmethod
|
| 974 |
+
def result_to_cif(result) -> str:
|
| 975 |
+
assert not isinstance(result, list), "Pass one MolecularComplexResult at a time."
|
| 976 |
+
return result.complex.to_mmcif()
|
| 977 |
+
|
| 978 |
+
@staticmethod
|
| 979 |
+
def result_to_pdb(result) -> str:
|
| 980 |
+
assert not isinstance(result, list), "Pass one MolecularComplexResult at a time."
|
| 981 |
+
return result.complex.to_protein_complex().to_pdb_string()
|
| 982 |
+
|
| 983 |
+
def save_as_cif(self, result, output_path: str | Path) -> None:
|
| 984 |
+
Path(output_path).write_text(self.result_to_cif(result))
|
| 985 |
+
|
| 986 |
+
def save_as_pdb(self, result, output_path: str | Path) -> None:
|
| 987 |
+
Path(output_path).write_text(self.result_to_pdb(result))
|
| 988 |
+
|
| 989 |
+
def infer_protein_as_cif(self, seq: str, **forward_kwargs) -> str:
|
| 990 |
+
return self.result_to_cif(self.fold_protein(seq, **forward_kwargs))
|
| 991 |
+
|
| 992 |
+
def infer_protein_as_pdb(self, seq: str, **forward_kwargs) -> str:
|
| 993 |
+
return self.result_to_pdb(self.fold_protein(seq, **forward_kwargs))
|
| 994 |
+
|
| 995 |
+
|
| 996 |
+
__all__ = [
|
| 997 |
+
"ConfidenceHead",
|
| 998 |
+
"MSAEncoder",
|
| 999 |
+
"MSAEncoderBlock",
|
| 1000 |
+
"ESMFold2ExperimentalModel",
|
| 1001 |
+
]
|
protein_utils.py
CHANGED
|
@@ -1,488 +1,488 @@
|
|
| 1 |
-
# coding=utf-8
|
| 2 |
-
# Copyright 2026 Biohub. All rights reserved.
|
| 3 |
-
#
|
| 4 |
-
# Licensed under the Apache License, Version 2.0 (the "License");
|
| 5 |
-
# you may not use this file except in compliance with the License.
|
| 6 |
-
# You may obtain a copy of the License at
|
| 7 |
-
#
|
| 8 |
-
# http://www.apache.org/licenses/LICENSE-2.0
|
| 9 |
-
#
|
| 10 |
-
# Unless required by applicable law or agreed to in writing, software
|
| 11 |
-
# distributed under the License is distributed on an "AS IS" BASIS,
|
| 12 |
-
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
| 13 |
-
# See the License for the specific language governing permissions and
|
| 14 |
-
# limitations under the License.
|
| 15 |
-
"""Self-contained protein featurization for ESMFold2 inference.
|
| 16 |
-
|
| 17 |
-
Lets ``ESMFold2ExperimentalModel.infer_protein_as_pdb`` fold a protein sequence
|
| 18 |
-
ESMFold-style without the ``esm`` companion package. The featurization
|
| 19 |
-
mirrors ``ESMFold2InputBuilder.prepare_input`` for the protein-only path —
|
| 20 |
-
``test_prepare_protein_features.py`` enforces tensor-exact parity.
|
| 21 |
-
"""
|
| 22 |
-
|
| 23 |
-
from __future__ import annotations
|
| 24 |
-
|
| 25 |
-
import math
|
| 26 |
-
|
| 27 |
-
import torch
|
| 28 |
-
from torch import Tensor
|
| 29 |
-
|
| 30 |
-
MOL_TYPE_PROTEIN = 0
|
| 31 |
-
PROTEIN_UNK_RES_TYPE = 22
|
| 32 |
-
MSA_GAP_TOKEN_ID = 1
|
| 33 |
-
|
| 34 |
-
PROTEIN_RESIDUE_TO_RES_TYPE: dict[str, int] = {
|
| 35 |
-
"ALA": 2,
|
| 36 |
-
"ARG": 3,
|
| 37 |
-
"ASN": 4,
|
| 38 |
-
"ASP": 5,
|
| 39 |
-
"CYS": 6,
|
| 40 |
-
"GLN": 7,
|
| 41 |
-
"GLU": 8,
|
| 42 |
-
"GLY": 9,
|
| 43 |
-
"HIS": 10,
|
| 44 |
-
"ILE": 11,
|
| 45 |
-
"LEU": 12,
|
| 46 |
-
"LYS": 13,
|
| 47 |
-
"MET": 14,
|
| 48 |
-
"PHE": 15,
|
| 49 |
-
"PRO": 16,
|
| 50 |
-
"SER": 17,
|
| 51 |
-
"THR": 18,
|
| 52 |
-
"TRP": 19,
|
| 53 |
-
"TYR": 20,
|
| 54 |
-
"VAL": 21,
|
| 55 |
-
}
|
| 56 |
-
|
| 57 |
-
PROTEIN_1TO3: dict[str, str] = {
|
| 58 |
-
"A": "ALA",
|
| 59 |
-
"R": "ARG",
|
| 60 |
-
"N": "ASN",
|
| 61 |
-
"D": "ASP",
|
| 62 |
-
"C": "CYS",
|
| 63 |
-
"Q": "GLN",
|
| 64 |
-
"E": "GLU",
|
| 65 |
-
"G": "GLY",
|
| 66 |
-
"H": "HIS",
|
| 67 |
-
"I": "ILE",
|
| 68 |
-
"L": "LEU",
|
| 69 |
-
"K": "LYS",
|
| 70 |
-
"M": "MET",
|
| 71 |
-
"F": "PHE",
|
| 72 |
-
"P": "PRO",
|
| 73 |
-
"S": "SER",
|
| 74 |
-
"T": "THR",
|
| 75 |
-
"W": "TRP",
|
| 76 |
-
"Y": "TYR",
|
| 77 |
-
"V": "VAL",
|
| 78 |
-
"X": "UNK",
|
| 79 |
-
}
|
| 80 |
-
|
| 81 |
-
ESM_PROTEIN_VOCAB: dict[str, int] = {
|
| 82 |
-
"L": 4,
|
| 83 |
-
"A": 5,
|
| 84 |
-
"G": 6,
|
| 85 |
-
"V": 7,
|
| 86 |
-
"S": 8,
|
| 87 |
-
"E": 9,
|
| 88 |
-
"R": 10,
|
| 89 |
-
"T": 11,
|
| 90 |
-
"I": 12,
|
| 91 |
-
"D": 13,
|
| 92 |
-
"P": 14,
|
| 93 |
-
"K": 15,
|
| 94 |
-
"Q": 16,
|
| 95 |
-
"N": 17,
|
| 96 |
-
"F": 18,
|
| 97 |
-
"Y": 19,
|
| 98 |
-
"M": 20,
|
| 99 |
-
"H": 21,
|
| 100 |
-
"W": 22,
|
| 101 |
-
"C": 23,
|
| 102 |
-
"X": 3,
|
| 103 |
-
}
|
| 104 |
-
|
| 105 |
-
# Heavy atoms per canonical residue, in training-time order.
|
| 106 |
-
PROTEIN_HEAVY_ATOMS: dict[str, list[str]] = {
|
| 107 |
-
"ALA": ["N", "CA", "C", "O", "CB"],
|
| 108 |
-
"ARG": ["N", "CA", "C", "O", "CB", "CG", "CD", "NE", "CZ", "NH1", "NH2"],
|
| 109 |
-
"ASN": ["N", "CA", "C", "O", "CB", "CG", "OD1", "ND2"],
|
| 110 |
-
"ASP": ["N", "CA", "C", "O", "CB", "CG", "OD1", "OD2"],
|
| 111 |
-
"CYS": ["N", "CA", "C", "O", "CB", "SG"],
|
| 112 |
-
"GLN": ["N", "CA", "C", "O", "CB", "CG", "CD", "OE1", "NE2"],
|
| 113 |
-
"GLU": ["N", "CA", "C", "O", "CB", "CG", "CD", "OE1", "OE2"],
|
| 114 |
-
"GLY": ["N", "CA", "C", "O"],
|
| 115 |
-
"HIS": ["N", "CA", "C", "O", "CB", "CG", "ND1", "CD2", "CE1", "NE2"],
|
| 116 |
-
"ILE": ["N", "CA", "C", "O", "CB", "CG1", "CG2", "CD1"],
|
| 117 |
-
"LEU": ["N", "CA", "C", "O", "CB", "CG", "CD1", "CD2"],
|
| 118 |
-
"LYS": ["N", "CA", "C", "O", "CB", "CG", "CD", "CE", "NZ"],
|
| 119 |
-
"MET": ["N", "CA", "C", "O", "CB", "CG", "SD", "CE"],
|
| 120 |
-
"PHE": ["N", "CA", "C", "O", "CB", "CG", "CD1", "CD2", "CE1", "CE2", "CZ"],
|
| 121 |
-
"PRO": ["N", "CA", "C", "O", "CB", "CG", "CD"],
|
| 122 |
-
"SER": ["N", "CA", "C", "O", "CB", "OG"],
|
| 123 |
-
"THR": ["N", "CA", "C", "O", "CB", "OG1", "CG2"],
|
| 124 |
-
"TRP": [
|
| 125 |
-
"N",
|
| 126 |
-
"CA",
|
| 127 |
-
"C",
|
| 128 |
-
"O",
|
| 129 |
-
"CB",
|
| 130 |
-
"CG",
|
| 131 |
-
"CD1",
|
| 132 |
-
"CD2",
|
| 133 |
-
"NE1",
|
| 134 |
-
"CE2",
|
| 135 |
-
"CE3",
|
| 136 |
-
"CZ2",
|
| 137 |
-
"CZ3",
|
| 138 |
-
"CH2",
|
| 139 |
-
],
|
| 140 |
-
"TYR": ["N", "CA", "C", "O", "CB", "CG", "CD1", "CD2", "CE1", "CE2", "CZ", "OH"],
|
| 141 |
-
"VAL": ["N", "CA", "C", "O", "CB", "CG1", "CG2"],
|
| 142 |
-
"UNK": ["N", "CA", "C", "O"],
|
| 143 |
-
}
|
| 144 |
-
|
| 145 |
-
PROTEIN_REF_POS: dict[str, dict[str, tuple[float, float, float]]] = {
|
| 146 |
-
"ALA": {
|
| 147 |
-
"N": (-0.01003183238208294, -1.2073018550872803, -1.0555061101913452),
|
| 148 |
-
"CA": (-0.04190138354897499, 0.17447763681411743, -0.5729365348815918),
|
| 149 |
-
"C": (1.2127548456192017, 0.4737588167190552, 0.19521640241146088),
|
| 150 |
-
"O": (1.9390329122543335, 1.4484562873840332, -0.13759790360927582),
|
| 151 |
-
"CB": (-1.276943325996399, 0.4288230538368225, 0.29937705397605896),
|
| 152 |
-
},
|
| 153 |
-
"ARG": {
|
| 154 |
-
"N": (-2.0170421600341797, 0.6717798113822937, -1.1794233322143555),
|
| 155 |
-
"CA": (-2.0503084659576416, -0.5735036730766296, -0.4097220301628113),
|
| 156 |
-
"C": (-3.469440460205078, -1.0612813234329224, -0.2755832374095917),
|
| 157 |
-
"O": (-3.8218462467193604, -2.1369943618774414, -0.8294969797134399),
|
| 158 |
-
"CB": (-1.4193516969680786, -0.3735991418361664, 0.9852858781814575),
|
| 159 |
-
"CG": (0.11878877878189087, -0.3112654983997345, 0.963895857334137),
|
| 160 |
-
"CD": (0.6643245816230774, 1.0068185329437256, 0.3963329493999481),
|
| 161 |
-
"NE": (2.1090238094329834, 1.0977025032043457, 0.6120952367782593),
|
| 162 |
-
"CZ": (3.098905324935913, 0.3215920031070709, -0.09047172218561172),
|
| 163 |
-
"NH1": (4.461230278015137, 0.3844667971134186, 0.34141138195991516),
|
| 164 |
-
"NH2": (2.7856509685516357, -0.4166366159915924, -1.1148239374160767),
|
| 165 |
-
},
|
| 166 |
-
"ASN": {
|
| 167 |
-
"N": (-0.7595629096031189, 0.7503494620323181, 1.1369825601577759),
|
| 168 |
-
"CA": (-0.76087886095047, 0.23876343667507172, -0.23573364317417145),
|
| 169 |
-
"C": (-1.9211044311523438, -0.6982439160346985, -0.42196929454803467),
|
| 170 |
-
"O": (-2.677666187286377, -0.5753439664840698, -1.4223182201385498),
|
| 171 |
-
"CB": (0.5504899024963379, -0.5078350305557251, -0.5390339493751526),
|
| 172 |
-
"CG": (1.7250099182128906, 0.4264017939567566, -0.5778228640556335),
|
| 173 |
-
"OD1": (1.9470350742340088, 1.1086392402648926, -1.613560438156128),
|
| 174 |
-
"ND2": (2.57365345954895, 0.5730618834495544, 0.5608599781990051),
|
| 175 |
-
},
|
| 176 |
-
"ASP": {
|
| 177 |
-
"N": (-1.8452696800231934, -1.2169504165649414, 0.19437327980995178),
|
| 178 |
-
"CA": (-0.6379959583282471, -0.41974392533302307, 0.41681644320487976),
|
| 179 |
-
"C": (-0.9431572556495667, 1.0356197357177734, 0.18555717170238495),
|
| 180 |
-
"O": (-1.5183608531951904, 1.4045922756195068, -0.8739855885505676),
|
| 181 |
-
"CB": (0.48594576120376587, -0.8970447778701782, -0.5209363698959351),
|
| 182 |
-
"CG": (1.780342936515808, -0.19918935000896454, -0.2310730367898941),
|
| 183 |
-
"OD1": (2.5202910900115967, -0.6044584512710571, 0.7049641013145447),
|
| 184 |
-
"OD2": (2.1454880237579346, 0.9208861589431763, -0.9712985157966614),
|
| 185 |
-
},
|
| 186 |
-
"CYS": {
|
| 187 |
-
"N": (0.0469963513314724, 1.190075159072876, -1.1607273817062378),
|
| 188 |
-
"CA": (0.11344368755817413, -0.09400428831577301, -0.45952197909355164),
|
| 189 |
-
"C": (-1.2652032375335693, -0.6832379698753357, -0.3594406247138977),
|
| 190 |
-
"O": (-1.4631439447402954, -1.8851220607757568, -0.6826791763305664),
|
| 191 |
-
"CB": (0.6919880509376526, 0.09034398198127747, 0.952482283115387),
|
| 192 |
-
"SG": (2.4619927406311035, 0.5235707759857178, 0.9020372629165649),
|
| 193 |
-
},
|
| 194 |
-
"GLN": {
|
| 195 |
-
"N": (-2.370004653930664, -0.9637529850006104, -0.7942749261856079),
|
| 196 |
-
"CA": (-1.370002269744873, -0.6000258922576904, 0.2103111445903778),
|
| 197 |
-
"C": (-1.7545503377914429, 0.7091967463493347, 0.8433493971824646),
|
| 198 |
-
"O": (-1.8520662784576416, 0.7999289631843567, 2.0964975357055664),
|
| 199 |
-
"CB": (0.02040259726345539, -0.5004461407661438, -0.44764479994773865),
|
| 200 |
-
"CG": (1.1377512216567993, -0.28680720925331116, 0.582992434501648),
|
| 201 |
-
"CD": (2.4745187759399414, -0.24800164997577667, -0.09364881366491318),
|
| 202 |
-
"OE1": (3.1685523986816406, -1.2966246604919434, -0.1717153936624527),
|
| 203 |
-
"NE2": (2.947425603866577, 0.9601329565048218, -0.6888364553451538),
|
| 204 |
-
},
|
| 205 |
-
"GLU": {
|
| 206 |
-
"N": (-1.5850872993469238, -1.337684154510498, 0.9490851163864136),
|
| 207 |
-
"CA": (-1.0560977458953857, 0.027459044009447098, 1.0306966304779053),
|
| 208 |
-
"C": (-1.7741456031799316, 0.9664392471313477, 0.09259600937366486),
|
| 209 |
-
"O": (-1.9012441635131836, 2.181349992752075, 0.402479350566864),
|
| 210 |
-
"CB": (0.4706551432609558, 0.048803869634866714, 0.8114414811134338),
|
| 211 |
-
"CG": (0.9133604764938354, -0.4219329059123993, -0.5830985307693481),
|
| 212 |
-
"CD": (2.398822069168091, -0.3097084164619446, -0.7210537791252136),
|
| 213 |
-
"OE1": (3.1389315128326416, -1.274524450302124, -0.39029765129089355),
|
| 214 |
-
"OE2": (2.9647817611694336, 0.8781346082687378, -1.1732689142227173),
|
| 215 |
-
},
|
| 216 |
-
"GLY": {
|
| 217 |
-
"N": (-1.3942985534667969, -0.39875128865242004, -0.3370324671268463),
|
| 218 |
-
"CA": (-0.39974430203437805, 0.5488945245742798, 0.15242962539196014),
|
| 219 |
-
"C": (0.9440054893493652, -0.10314033925533295, 0.19859643280506134),
|
| 220 |
-
"O": (1.3352899551391602, -0.669218122959137, 1.2541258335113525),
|
| 221 |
-
},
|
| 222 |
-
"HIS": {
|
| 223 |
-
"N": (-1.4532867670059204, -1.0689626932144165, 0.881072461605072),
|
| 224 |
-
"CA": (-1.3396095037460327, 0.24797579646110535, 0.24960045516490936),
|
| 225 |
-
"C": (-2.675257921218872, 0.6571555733680725, -0.30441102385520935),
|
| 226 |
-
"O": (-3.1311378479003906, 1.8079776763916016, -0.06785715371370316),
|
| 227 |
-
"CB": (-0.3041955828666687, 0.21721023321151733, -0.8885309100151062),
|
| 228 |
-
"CG": (1.0887513160705566, 0.028941065073013306, -0.36419469118118286),
|
| 229 |
-
"ND1": (1.840459942817688, 1.0411773920059204, 0.29804590344429016),
|
| 230 |
-
"CD2": (1.780855417251587, -1.1011489629745483, -0.3814258575439453),
|
| 231 |
-
"CE1": (2.9566943645477295, 0.4924798905849457, 0.6477115750312805),
|
| 232 |
-
"NE2": (3.0280203819274902, -0.8751969337463379, 0.26084381341934204),
|
| 233 |
-
},
|
| 234 |
-
"ILE": {
|
| 235 |
-
"N": (-0.7167549729347229, -1.5426139831542969, -0.9983330368995667),
|
| 236 |
-
"CA": (-1.0636085271835327, -0.35169270634651184, -0.21393552422523499),
|
| 237 |
-
"C": (-1.3896740674972534, 0.8142145276069641, -1.1164065599441528),
|
| 238 |
-
"O": (-1.2377792596817017, 0.7302915453910828, -2.3656840324401855),
|
| 239 |
-
"CB": (0.061667006462812424, 0.01599610224366188, 0.8057394623756409),
|
| 240 |
-
"CG1": (1.502519965171814, -0.08899776637554169, 0.24154816567897797),
|
| 241 |
-
"CG2": (-0.053174979984760284, -0.8521055579185486, 2.0702083110809326),
|
| 242 |
-
"CD1": (1.7929610013961792, 0.899773120880127, -0.8863027691841125),
|
| 243 |
-
},
|
| 244 |
-
"LEU": {
|
| 245 |
-
"N": (1.9657520055770874, -1.9763224124908447, -0.18391533195972443),
|
| 246 |
-
"CA": (1.3077669143676758, -0.6677430868148804, -0.19492436945438385),
|
| 247 |
-
"C": (1.9905058145523071, 0.24182087182998657, 0.7879968285560608),
|
| 248 |
-
"O": (2.06896710395813, -0.07880014181137085, 2.0048046112060547),
|
| 249 |
-
"CB": (-0.20306941866874695, -0.8093230128288269, 0.11243502795696259),
|
| 250 |
-
"CG": (-0.9916267395019531, 0.5234957337379456, 0.06723011285066605),
|
| 251 |
-
"CD1": (-2.4228057861328125, 0.29949337244033813, 0.573042094707489),
|
| 252 |
-
"CD2": (-1.0282856225967407, 1.1250264644622803, -1.346014380455017),
|
| 253 |
-
},
|
| 254 |
-
"LYS": {
|
| 255 |
-
"N": (2.4221372604370117, -0.6473312377929688, 0.6370573043823242),
|
| 256 |
-
"CA": (2.0314927101135254, 0.2786507308483124, -0.4298512041568756),
|
| 257 |
-
"C": (2.7168593406677246, 1.595757246017456, -0.20924785733222961),
|
| 258 |
-
"O": (3.397681713104248, 2.116427421569824, -1.1332510709762573),
|
| 259 |
-
"CB": (0.5018402934074402, 0.4873858690261841, -0.49062973260879517),
|
| 260 |
-
"CG": (-0.25062066316604614, -0.7894009947776794, -0.9055535793304443),
|
| 261 |
-
"CD": (-1.769762635231018, -0.5552700161933899, -1.040329933166504),
|
| 262 |
-
"CE": (-2.576533555984497, -1.0221366882324219, 0.18493641912937164),
|
| 263 |
-
"NZ": (-2.269151210784912, -0.24293844401836395, 1.3849012851715088),
|
| 264 |
-
},
|
| 265 |
-
"MET": {
|
| 266 |
-
"N": (1.8903918266296387, -1.5252995491027832, -0.42638593912124634),
|
| 267 |
-
"CA": (1.2630571126937866, -0.24417810142040253, -0.7626462578773499),
|
| 268 |
-
"C": (2.30391001701355, 0.8367712497711182, -0.7254616618156433),
|
| 269 |
-
"O": (2.465414524078369, 1.5928632020950317, -1.7207728624343872),
|
| 270 |
-
"CB": (0.10567972809076309, 0.10861825942993164, 0.19741646945476532),
|
| 271 |
-
"CG": (-1.0658042430877686, -0.8736631274223328, 0.08811883628368378),
|
| 272 |
-
"SD": (-2.4557132720947266, -0.3332225978374481, 1.1461700201034546),
|
| 273 |
-
"CE": (-3.265165090560913, 0.7033554911613464, -0.11588376015424728),
|
| 274 |
-
},
|
| 275 |
-
"PHE": {
|
| 276 |
-
"N": (-2.8484435081481934, -1.525790810585022, 0.01789816841483116),
|
| 277 |
-
"CA": (-1.591969609260559, -0.8545162677764893, 0.35214468836784363),
|
| 278 |
-
"C": (-1.8900631666183472, 0.45833414793014526, 1.0232222080230713),
|
| 279 |
-
"O": (-1.3424992561340332, 0.74432373046875, 2.121629476547241),
|
| 280 |
-
"CB": (-0.760358452796936, -0.6342853307723999, -0.9257160425186157),
|
| 281 |
-
"CG": (0.604112982749939, -0.07200468331575394, -0.6148118376731873),
|
| 282 |
-
"CD1": (0.8468314409255981, 1.2480632066726685, -0.7146694660186768),
|
| 283 |
-
"CD2": (1.6827683448791504, -0.9758077263832092, -0.1423054188489914),
|
| 284 |
-
"CE1": (2.1801748275756836, 1.7875733375549316, -0.3744623064994812),
|
| 285 |
-
"CE2": (2.888307809829712, -0.48277512192726135, 0.16804970800876617),
|
| 286 |
-
"CZ": (3.149812936782837, 0.9656873941421509, 0.04440271109342575),
|
| 287 |
-
},
|
| 288 |
-
"PRO": {
|
| 289 |
-
"N": (-0.836250364780426, -0.9899801015853882, 0.5561304688453674),
|
| 290 |
-
"CA": (0.32722190022468567, -0.6164458394050598, -0.25072571635246277),
|
| 291 |
-
"C": (1.6121541261672974, -1.1711241006851196, 0.31082412600517273),
|
| 292 |
-
"O": (1.6127740144729614, -2.2771971225738525, 0.9156193733215332),
|
| 293 |
-
"CB": (0.3248198926448822, 0.9028244018554688, -0.33368146419525146),
|
| 294 |
-
"CG": (-1.1425083875656128, 1.2730128765106201, -0.2590600252151489),
|
| 295 |
-
"CD": (-1.8495968580245972, 0.026575811207294464, 0.2681289613246918),
|
| 296 |
-
},
|
| 297 |
-
"SER": {
|
| 298 |
-
"N": (0.674650251865387, 1.5018702745437622, -0.5367295145988464),
|
| 299 |
-
"CA": (0.00013792862591799349, 0.4966467022895813, 0.28510504961013794),
|
| 300 |
-
"C": (0.9941009879112244, -0.5374617576599121, 0.73505038022995),
|
| 301 |
-
"O": (1.0545241832733154, -0.8683545589447021, 1.9495396614074707),
|
| 302 |
-
"CB": (-1.1279288530349731, -0.1659376323223114, -0.5160963535308838),
|
| 303 |
-
"OG": (-1.8135979175567627, -1.085249662399292, 0.28947514295578003),
|
| 304 |
-
},
|
| 305 |
-
"THR": {
|
| 306 |
-
"N": (-1.325830340385437, -1.3728225231170654, 0.6882233023643494),
|
| 307 |
-
"CA": (-0.5433306097984314, -0.16364754736423492, 0.41697052121162415),
|
| 308 |
-
"C": (-1.294381856918335, 0.7077372074127197, -0.5549946427345276),
|
| 309 |
-
"O": (-1.6939635276794434, 0.23654410243034363, -1.6540418863296509),
|
| 310 |
-
"CB": (0.853203296661377, -0.5363803505897522, -0.14109353721141815),
|
| 311 |
-
"OG1": (1.5220820903778076, -1.379003643989563, 0.7635167837142944),
|
| 312 |
-
"CG2": (1.7225933074951172, 0.7054727077484131, -0.3651331067085266),
|
| 313 |
-
},
|
| 314 |
-
"TRP": {
|
| 315 |
-
"N": (3.686030864715576, 0.7599999904632568, 0.496155709028244),
|
| 316 |
-
"CA": (2.384092092514038, 0.09079249948263168, 0.5325262546539307),
|
| 317 |
-
"C": (2.1113572120666504, -0.6121063232421875, -0.7733646035194397),
|
| 318 |
-
"O": (1.796526312828064, -1.8323148488998413, -0.7775964140892029),
|
| 319 |
-
"CB": (1.281521201133728, 1.1139036417007446, 0.8559791445732117),
|
| 320 |
-
"CG": (-0.04292375594377518, 0.44645074009895325, 1.0942792892456055),
|
| 321 |
-
"CD1": (-0.42329534888267517, -0.15470874309539795, 2.2227554321289062),
|
| 322 |
-
"CD2": (-1.1023900508880615, 0.2158389836549759, 0.11529432237148285),
|
| 323 |
-
"NE1": (-1.7030320167541504, -0.7665823101997375, 2.0595016479492188),
|
| 324 |
-
"CE2": (-2.045644998550415, -0.4881173074245453, 0.710669219493866),
|
| 325 |
-
"CE3": (-1.2173502445220947, 0.6102271676063538, -1.300106406211853),
|
| 326 |
-
"CZ2": (-3.256009340286255, -0.9164394736289978, -0.00984987337142229),
|
| 327 |
-
"CZ3": (-2.315925121307373, 0.2306906282901764, -1.9776310920715332),
|
| 328 |
-
"CH2": (-3.3817875385284424, -0.5677337646484375, -1.3032053709030151),
|
| 329 |
-
},
|
| 330 |
-
"TYR": {
|
| 331 |
-
"N": (-1.7900604009628296, -0.8409399390220642, 1.3180142641067505),
|
| 332 |
-
"CA": (-1.913882851600647, 0.23552845418453217, 0.330669641494751),
|
| 333 |
-
"C": (-3.347280740737915, 0.3588399887084961, -0.09830684959888458),
|
| 334 |
-
"O": (-3.967811346054077, -0.6449354290962219, -0.5423302054405212),
|
| 335 |
-
"CB": (-1.0093992948532104, 0.0004731413209810853, -0.8981552124023438),
|
| 336 |
-
"CG": (0.4520410895347595, 0.021162061020731926, -0.5305932760238647),
|
| 337 |
-
"CD1": (1.0992432832717896, 1.1877919435501099, -0.3579142987728119),
|
| 338 |
-
"CD2": (1.1803174018859863, -1.253401279449463, -0.31122180819511414),
|
| 339 |
-
"CE1": (2.5253450870513916, 1.1990256309509277, 0.029804613441228867),
|
| 340 |
-
"CE2": (2.471151113510132, -1.240687608718872, 0.043534230440855026),
|
| 341 |
-
"CZ": (3.180687665939331, 0.04672492295503616, 0.2214856892824173),
|
| 342 |
-
"OH": (4.523719787597656, 0.0671030730009079, 0.5877485871315002),
|
| 343 |
-
},
|
| 344 |
-
"VAL": {
|
| 345 |
-
"N": (0.5987519025802612, -1.569443702697754, -0.7379124760627747),
|
| 346 |
-
"CA": (0.6014357209205627, -0.10503966361284256, -0.6336286664009094),
|
| 347 |
-
"C": (1.8391697406768799, 0.4067850410938263, 0.06351757049560547),
|
| 348 |
-
"O": (2.3952062129974365, -0.2666190266609192, 0.9731166958808899),
|
| 349 |
-
"CB": (-0.694736897945404, 0.4259096384048462, 0.03581475466489792),
|
| 350 |
-
"CG1": (-1.9276031255722046, 0.09515828639268875, -0.8172357082366943),
|
| 351 |
-
"CG2": (-0.8938426971435547, -0.08640842139720917, 1.472349762916565),
|
| 352 |
-
},
|
| 353 |
-
"UNK": {
|
| 354 |
-
"N": (0.0, 0.0, 0.0),
|
| 355 |
-
"CA": (0.0, 0.0, 0.0),
|
| 356 |
-
"C": (0.0, 0.0, 0.0),
|
| 357 |
-
"O": (0.0, 0.0, 0.0),
|
| 358 |
-
},
|
| 359 |
-
}
|
| 360 |
-
|
| 361 |
-
# Protonated nitrogens at physiological pH (matches CHARGED_ATOMS in the
|
| 362 |
-
# opensource constants for the protein subset).
|
| 363 |
-
PROTEIN_CHARGED_ATOMS: dict[tuple[str, str], int] = {
|
| 364 |
-
("LYS", "NZ"): 1,
|
| 365 |
-
("ARG", "NH2"): 1,
|
| 366 |
-
("HIS", "ND1"): 1,
|
| 367 |
-
}
|
| 368 |
-
|
| 369 |
-
# Only the elements that appear in canonical protein heavy atoms.
|
| 370 |
-
_PROTEIN_ELEMENT_TO_ATOMIC_NUM: dict[str, int] = {"C": 6, "N": 7, "O": 8, "S": 16}
|
| 371 |
-
|
| 372 |
-
|
| 373 |
-
def _encode_atom_name(name: str) -> list[int]:
|
| 374 |
-
padded = name.ljust(4)[:4]
|
| 375 |
-
return [ord(c) - 32 if c != " " else 0 for c in padded]
|
| 376 |
-
|
| 377 |
-
|
| 378 |
-
def prepare_protein_features(sequence: str) -> dict[str, Tensor]:
|
| 379 |
-
"""Featurize a single protein sequence for ESMFold2ExperimentalModel.forward.
|
| 380 |
-
|
| 381 |
-
Returns the same keys with the same dtypes/shapes as
|
| 382 |
-
``ESMFold2InputBuilder.prepare_input(StructurePredictionInput(...))``
|
| 383 |
-
restricted to a single-chain protein with no MSA, modifications,
|
| 384 |
-
distogram conditioning, or covalent bonds. All tensors have a
|
| 385 |
-
leading batch dim of 1; the caller is responsible for moving them
|
| 386 |
-
to the model device.
|
| 387 |
-
"""
|
| 388 |
-
if not sequence:
|
| 389 |
-
raise ValueError("sequence must be non-empty")
|
| 390 |
-
|
| 391 |
-
res_3letter = [PROTEIN_1TO3.get(c, "UNK") for c in sequence]
|
| 392 |
-
L = len(sequence)
|
| 393 |
-
|
| 394 |
-
token_atom_starts: list[int] = []
|
| 395 |
-
atom_records: list[tuple[int, str, str, int, tuple[float, float, float]]] = []
|
| 396 |
-
res_type_vals: list[int] = []
|
| 397 |
-
input_id_vals: list[int] = []
|
| 398 |
-
distogram_rep_atom_idx: list[int] = []
|
| 399 |
-
|
| 400 |
-
atom_cursor = 0
|
| 401 |
-
for t_idx, (letter, res_3) in enumerate(zip(sequence, res_3letter)):
|
| 402 |
-
atom_names = PROTEIN_HEAVY_ATOMS[res_3]
|
| 403 |
-
res_type = PROTEIN_RESIDUE_TO_RES_TYPE.get(res_3, PROTEIN_UNK_RES_TYPE)
|
| 404 |
-
input_id = ESM_PROTEIN_VOCAB.get(letter, ESM_PROTEIN_VOCAB["X"])
|
| 405 |
-
|
| 406 |
-
token_atom_starts.append(atom_cursor)
|
| 407 |
-
for name in atom_names:
|
| 408 |
-
charge = PROTEIN_CHARGED_ATOMS.get((res_3, name), 0)
|
| 409 |
-
element = name[0] # protein heavy atoms are all single-letter C/N/O/S
|
| 410 |
-
ref_pos = PROTEIN_REF_POS[res_3][name]
|
| 411 |
-
atom_records.append((t_idx, name, element, charge, ref_pos))
|
| 412 |
-
atom_cursor += 1
|
| 413 |
-
|
| 414 |
-
rep_name = "CB" if "CB" in atom_names else "CA"
|
| 415 |
-
distogram_rep_atom_idx.append(
|
| 416 |
-
token_atom_starts[t_idx] + atom_names.index(rep_name)
|
| 417 |
-
)
|
| 418 |
-
|
| 419 |
-
res_type_vals.append(res_type)
|
| 420 |
-
input_id_vals.append(input_id)
|
| 421 |
-
|
| 422 |
-
n_real_atoms = len(atom_records)
|
| 423 |
-
n_atoms = math.ceil(n_real_atoms / 32) * 32 if n_real_atoms > 0 else 32
|
| 424 |
-
|
| 425 |
-
ref_pos = torch.zeros(n_atoms, 3, dtype=torch.float32)
|
| 426 |
-
ref_element = torch.zeros(n_atoms, dtype=torch.int64)
|
| 427 |
-
ref_charge = torch.zeros(n_atoms, dtype=torch.int8)
|
| 428 |
-
ref_atom_name_chars = torch.zeros(n_atoms, 4, dtype=torch.int64)
|
| 429 |
-
ref_space_uid = torch.zeros(n_atoms, dtype=torch.int64)
|
| 430 |
-
atom_attention_mask = torch.zeros(n_atoms, dtype=torch.bool)
|
| 431 |
-
atom_to_token = torch.zeros(n_atoms, dtype=torch.int64)
|
| 432 |
-
|
| 433 |
-
for i, (t_idx, name, element, charge, pos) in enumerate(atom_records):
|
| 434 |
-
ref_pos[i] = torch.tensor(pos, dtype=torch.float32)
|
| 435 |
-
ref_element[i] = _PROTEIN_ELEMENT_TO_ATOMIC_NUM[element]
|
| 436 |
-
ref_charge[i] = charge
|
| 437 |
-
ref_atom_name_chars[i] = torch.tensor(
|
| 438 |
-
_encode_atom_name(name), dtype=torch.int64
|
| 439 |
-
)
|
| 440 |
-
ref_space_uid[i] = t_idx
|
| 441 |
-
atom_attention_mask[i] = True
|
| 442 |
-
atom_to_token[i] = t_idx
|
| 443 |
-
|
| 444 |
-
token_index = torch.arange(L, dtype=torch.int64)
|
| 445 |
-
residue_index = torch.arange(L, dtype=torch.int64)
|
| 446 |
-
asym_id = torch.zeros(L, dtype=torch.int64)
|
| 447 |
-
sym_id = torch.zeros(L, dtype=torch.int64)
|
| 448 |
-
entity_id = torch.ones(L, dtype=torch.int64)
|
| 449 |
-
mol_type = torch.full((L,), MOL_TYPE_PROTEIN, dtype=torch.int64)
|
| 450 |
-
res_type = torch.tensor(res_type_vals, dtype=torch.int64)
|
| 451 |
-
input_ids = torch.tensor(input_id_vals, dtype=torch.int64)
|
| 452 |
-
token_bonds = torch.zeros(L, L, 1, dtype=torch.float32)
|
| 453 |
-
token_attention_mask = torch.ones(L, dtype=torch.bool)
|
| 454 |
-
distogram_atom_idx = torch.tensor(distogram_rep_atom_idx, dtype=torch.int64)
|
| 455 |
-
|
| 456 |
-
# Single-sequence MSA: depth 1, row 0 is the sequence itself.
|
| 457 |
-
msa = res_type.unsqueeze(0)
|
| 458 |
-
msa_attention_mask = torch.ones(1, L, dtype=torch.bool)
|
| 459 |
-
has_deletion = torch.zeros(1, L, dtype=torch.bool)
|
| 460 |
-
deletion_value = torch.zeros(1, L, dtype=torch.float32)
|
| 461 |
-
deletion_mean = torch.zeros(L, dtype=torch.float32)
|
| 462 |
-
|
| 463 |
-
features = {
|
| 464 |
-
"token_index": token_index,
|
| 465 |
-
"residue_index": residue_index,
|
| 466 |
-
"asym_id": asym_id,
|
| 467 |
-
"sym_id": sym_id,
|
| 468 |
-
"entity_id": entity_id,
|
| 469 |
-
"mol_type": mol_type,
|
| 470 |
-
"res_type": res_type,
|
| 471 |
-
"input_ids": input_ids,
|
| 472 |
-
"token_bonds": token_bonds,
|
| 473 |
-
"token_attention_mask": token_attention_mask,
|
| 474 |
-
"ref_pos": ref_pos,
|
| 475 |
-
"ref_element": ref_element,
|
| 476 |
-
"ref_charge": ref_charge,
|
| 477 |
-
"ref_atom_name_chars": ref_atom_name_chars,
|
| 478 |
-
"ref_space_uid": ref_space_uid,
|
| 479 |
-
"atom_attention_mask": atom_attention_mask,
|
| 480 |
-
"atom_to_token": atom_to_token,
|
| 481 |
-
"distogram_atom_idx": distogram_atom_idx,
|
| 482 |
-
"msa": msa,
|
| 483 |
-
"msa_attention_mask": msa_attention_mask,
|
| 484 |
-
"has_deletion": has_deletion,
|
| 485 |
-
"deletion_value": deletion_value,
|
| 486 |
-
"deletion_mean": deletion_mean,
|
| 487 |
-
}
|
| 488 |
-
return {k: v.unsqueeze(0) for k, v in features.items()}
|
|
|
|
| 1 |
+
# coding=utf-8
|
| 2 |
+
# Copyright 2026 Biohub. All rights reserved.
|
| 3 |
+
#
|
| 4 |
+
# Licensed under the Apache License, Version 2.0 (the "License");
|
| 5 |
+
# you may not use this file except in compliance with the License.
|
| 6 |
+
# You may obtain a copy of the License at
|
| 7 |
+
#
|
| 8 |
+
# http://www.apache.org/licenses/LICENSE-2.0
|
| 9 |
+
#
|
| 10 |
+
# Unless required by applicable law or agreed to in writing, software
|
| 11 |
+
# distributed under the License is distributed on an "AS IS" BASIS,
|
| 12 |
+
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
| 13 |
+
# See the License for the specific language governing permissions and
|
| 14 |
+
# limitations under the License.
|
| 15 |
+
"""Self-contained protein featurization for ESMFold2 inference.
|
| 16 |
+
|
| 17 |
+
Lets ``ESMFold2ExperimentalModel.infer_protein_as_pdb`` fold a protein sequence
|
| 18 |
+
ESMFold-style without the ``esm`` companion package. The featurization
|
| 19 |
+
mirrors ``ESMFold2InputBuilder.prepare_input`` for the protein-only path —
|
| 20 |
+
``test_prepare_protein_features.py`` enforces tensor-exact parity.
|
| 21 |
+
"""
|
| 22 |
+
|
| 23 |
+
from __future__ import annotations
|
| 24 |
+
|
| 25 |
+
import math
|
| 26 |
+
|
| 27 |
+
import torch
|
| 28 |
+
from torch import Tensor
|
| 29 |
+
|
| 30 |
+
MOL_TYPE_PROTEIN = 0
|
| 31 |
+
PROTEIN_UNK_RES_TYPE = 22
|
| 32 |
+
MSA_GAP_TOKEN_ID = 1
|
| 33 |
+
|
| 34 |
+
PROTEIN_RESIDUE_TO_RES_TYPE: dict[str, int] = {
|
| 35 |
+
"ALA": 2,
|
| 36 |
+
"ARG": 3,
|
| 37 |
+
"ASN": 4,
|
| 38 |
+
"ASP": 5,
|
| 39 |
+
"CYS": 6,
|
| 40 |
+
"GLN": 7,
|
| 41 |
+
"GLU": 8,
|
| 42 |
+
"GLY": 9,
|
| 43 |
+
"HIS": 10,
|
| 44 |
+
"ILE": 11,
|
| 45 |
+
"LEU": 12,
|
| 46 |
+
"LYS": 13,
|
| 47 |
+
"MET": 14,
|
| 48 |
+
"PHE": 15,
|
| 49 |
+
"PRO": 16,
|
| 50 |
+
"SER": 17,
|
| 51 |
+
"THR": 18,
|
| 52 |
+
"TRP": 19,
|
| 53 |
+
"TYR": 20,
|
| 54 |
+
"VAL": 21,
|
| 55 |
+
}
|
| 56 |
+
|
| 57 |
+
PROTEIN_1TO3: dict[str, str] = {
|
| 58 |
+
"A": "ALA",
|
| 59 |
+
"R": "ARG",
|
| 60 |
+
"N": "ASN",
|
| 61 |
+
"D": "ASP",
|
| 62 |
+
"C": "CYS",
|
| 63 |
+
"Q": "GLN",
|
| 64 |
+
"E": "GLU",
|
| 65 |
+
"G": "GLY",
|
| 66 |
+
"H": "HIS",
|
| 67 |
+
"I": "ILE",
|
| 68 |
+
"L": "LEU",
|
| 69 |
+
"K": "LYS",
|
| 70 |
+
"M": "MET",
|
| 71 |
+
"F": "PHE",
|
| 72 |
+
"P": "PRO",
|
| 73 |
+
"S": "SER",
|
| 74 |
+
"T": "THR",
|
| 75 |
+
"W": "TRP",
|
| 76 |
+
"Y": "TYR",
|
| 77 |
+
"V": "VAL",
|
| 78 |
+
"X": "UNK",
|
| 79 |
+
}
|
| 80 |
+
|
| 81 |
+
ESM_PROTEIN_VOCAB: dict[str, int] = {
|
| 82 |
+
"L": 4,
|
| 83 |
+
"A": 5,
|
| 84 |
+
"G": 6,
|
| 85 |
+
"V": 7,
|
| 86 |
+
"S": 8,
|
| 87 |
+
"E": 9,
|
| 88 |
+
"R": 10,
|
| 89 |
+
"T": 11,
|
| 90 |
+
"I": 12,
|
| 91 |
+
"D": 13,
|
| 92 |
+
"P": 14,
|
| 93 |
+
"K": 15,
|
| 94 |
+
"Q": 16,
|
| 95 |
+
"N": 17,
|
| 96 |
+
"F": 18,
|
| 97 |
+
"Y": 19,
|
| 98 |
+
"M": 20,
|
| 99 |
+
"H": 21,
|
| 100 |
+
"W": 22,
|
| 101 |
+
"C": 23,
|
| 102 |
+
"X": 3,
|
| 103 |
+
}
|
| 104 |
+
|
| 105 |
+
# Heavy atoms per canonical residue, in training-time order.
|
| 106 |
+
PROTEIN_HEAVY_ATOMS: dict[str, list[str]] = {
|
| 107 |
+
"ALA": ["N", "CA", "C", "O", "CB"],
|
| 108 |
+
"ARG": ["N", "CA", "C", "O", "CB", "CG", "CD", "NE", "CZ", "NH1", "NH2"],
|
| 109 |
+
"ASN": ["N", "CA", "C", "O", "CB", "CG", "OD1", "ND2"],
|
| 110 |
+
"ASP": ["N", "CA", "C", "O", "CB", "CG", "OD1", "OD2"],
|
| 111 |
+
"CYS": ["N", "CA", "C", "O", "CB", "SG"],
|
| 112 |
+
"GLN": ["N", "CA", "C", "O", "CB", "CG", "CD", "OE1", "NE2"],
|
| 113 |
+
"GLU": ["N", "CA", "C", "O", "CB", "CG", "CD", "OE1", "OE2"],
|
| 114 |
+
"GLY": ["N", "CA", "C", "O"],
|
| 115 |
+
"HIS": ["N", "CA", "C", "O", "CB", "CG", "ND1", "CD2", "CE1", "NE2"],
|
| 116 |
+
"ILE": ["N", "CA", "C", "O", "CB", "CG1", "CG2", "CD1"],
|
| 117 |
+
"LEU": ["N", "CA", "C", "O", "CB", "CG", "CD1", "CD2"],
|
| 118 |
+
"LYS": ["N", "CA", "C", "O", "CB", "CG", "CD", "CE", "NZ"],
|
| 119 |
+
"MET": ["N", "CA", "C", "O", "CB", "CG", "SD", "CE"],
|
| 120 |
+
"PHE": ["N", "CA", "C", "O", "CB", "CG", "CD1", "CD2", "CE1", "CE2", "CZ"],
|
| 121 |
+
"PRO": ["N", "CA", "C", "O", "CB", "CG", "CD"],
|
| 122 |
+
"SER": ["N", "CA", "C", "O", "CB", "OG"],
|
| 123 |
+
"THR": ["N", "CA", "C", "O", "CB", "OG1", "CG2"],
|
| 124 |
+
"TRP": [
|
| 125 |
+
"N",
|
| 126 |
+
"CA",
|
| 127 |
+
"C",
|
| 128 |
+
"O",
|
| 129 |
+
"CB",
|
| 130 |
+
"CG",
|
| 131 |
+
"CD1",
|
| 132 |
+
"CD2",
|
| 133 |
+
"NE1",
|
| 134 |
+
"CE2",
|
| 135 |
+
"CE3",
|
| 136 |
+
"CZ2",
|
| 137 |
+
"CZ3",
|
| 138 |
+
"CH2",
|
| 139 |
+
],
|
| 140 |
+
"TYR": ["N", "CA", "C", "O", "CB", "CG", "CD1", "CD2", "CE1", "CE2", "CZ", "OH"],
|
| 141 |
+
"VAL": ["N", "CA", "C", "O", "CB", "CG1", "CG2"],
|
| 142 |
+
"UNK": ["N", "CA", "C", "O"],
|
| 143 |
+
}
|
| 144 |
+
|
| 145 |
+
PROTEIN_REF_POS: dict[str, dict[str, tuple[float, float, float]]] = {
|
| 146 |
+
"ALA": {
|
| 147 |
+
"N": (-0.01003183238208294, -1.2073018550872803, -1.0555061101913452),
|
| 148 |
+
"CA": (-0.04190138354897499, 0.17447763681411743, -0.5729365348815918),
|
| 149 |
+
"C": (1.2127548456192017, 0.4737588167190552, 0.19521640241146088),
|
| 150 |
+
"O": (1.9390329122543335, 1.4484562873840332, -0.13759790360927582),
|
| 151 |
+
"CB": (-1.276943325996399, 0.4288230538368225, 0.29937705397605896),
|
| 152 |
+
},
|
| 153 |
+
"ARG": {
|
| 154 |
+
"N": (-2.0170421600341797, 0.6717798113822937, -1.1794233322143555),
|
| 155 |
+
"CA": (-2.0503084659576416, -0.5735036730766296, -0.4097220301628113),
|
| 156 |
+
"C": (-3.469440460205078, -1.0612813234329224, -0.2755832374095917),
|
| 157 |
+
"O": (-3.8218462467193604, -2.1369943618774414, -0.8294969797134399),
|
| 158 |
+
"CB": (-1.4193516969680786, -0.3735991418361664, 0.9852858781814575),
|
| 159 |
+
"CG": (0.11878877878189087, -0.3112654983997345, 0.963895857334137),
|
| 160 |
+
"CD": (0.6643245816230774, 1.0068185329437256, 0.3963329493999481),
|
| 161 |
+
"NE": (2.1090238094329834, 1.0977025032043457, 0.6120952367782593),
|
| 162 |
+
"CZ": (3.098905324935913, 0.3215920031070709, -0.09047172218561172),
|
| 163 |
+
"NH1": (4.461230278015137, 0.3844667971134186, 0.34141138195991516),
|
| 164 |
+
"NH2": (2.7856509685516357, -0.4166366159915924, -1.1148239374160767),
|
| 165 |
+
},
|
| 166 |
+
"ASN": {
|
| 167 |
+
"N": (-0.7595629096031189, 0.7503494620323181, 1.1369825601577759),
|
| 168 |
+
"CA": (-0.76087886095047, 0.23876343667507172, -0.23573364317417145),
|
| 169 |
+
"C": (-1.9211044311523438, -0.6982439160346985, -0.42196929454803467),
|
| 170 |
+
"O": (-2.677666187286377, -0.5753439664840698, -1.4223182201385498),
|
| 171 |
+
"CB": (0.5504899024963379, -0.5078350305557251, -0.5390339493751526),
|
| 172 |
+
"CG": (1.7250099182128906, 0.4264017939567566, -0.5778228640556335),
|
| 173 |
+
"OD1": (1.9470350742340088, 1.1086392402648926, -1.613560438156128),
|
| 174 |
+
"ND2": (2.57365345954895, 0.5730618834495544, 0.5608599781990051),
|
| 175 |
+
},
|
| 176 |
+
"ASP": {
|
| 177 |
+
"N": (-1.8452696800231934, -1.2169504165649414, 0.19437327980995178),
|
| 178 |
+
"CA": (-0.6379959583282471, -0.41974392533302307, 0.41681644320487976),
|
| 179 |
+
"C": (-0.9431572556495667, 1.0356197357177734, 0.18555717170238495),
|
| 180 |
+
"O": (-1.5183608531951904, 1.4045922756195068, -0.8739855885505676),
|
| 181 |
+
"CB": (0.48594576120376587, -0.8970447778701782, -0.5209363698959351),
|
| 182 |
+
"CG": (1.780342936515808, -0.19918935000896454, -0.2310730367898941),
|
| 183 |
+
"OD1": (2.5202910900115967, -0.6044584512710571, 0.7049641013145447),
|
| 184 |
+
"OD2": (2.1454880237579346, 0.9208861589431763, -0.9712985157966614),
|
| 185 |
+
},
|
| 186 |
+
"CYS": {
|
| 187 |
+
"N": (0.0469963513314724, 1.190075159072876, -1.1607273817062378),
|
| 188 |
+
"CA": (0.11344368755817413, -0.09400428831577301, -0.45952197909355164),
|
| 189 |
+
"C": (-1.2652032375335693, -0.6832379698753357, -0.3594406247138977),
|
| 190 |
+
"O": (-1.4631439447402954, -1.8851220607757568, -0.6826791763305664),
|
| 191 |
+
"CB": (0.6919880509376526, 0.09034398198127747, 0.952482283115387),
|
| 192 |
+
"SG": (2.4619927406311035, 0.5235707759857178, 0.9020372629165649),
|
| 193 |
+
},
|
| 194 |
+
"GLN": {
|
| 195 |
+
"N": (-2.370004653930664, -0.9637529850006104, -0.7942749261856079),
|
| 196 |
+
"CA": (-1.370002269744873, -0.6000258922576904, 0.2103111445903778),
|
| 197 |
+
"C": (-1.7545503377914429, 0.7091967463493347, 0.8433493971824646),
|
| 198 |
+
"O": (-1.8520662784576416, 0.7999289631843567, 2.0964975357055664),
|
| 199 |
+
"CB": (0.02040259726345539, -0.5004461407661438, -0.44764479994773865),
|
| 200 |
+
"CG": (1.1377512216567993, -0.28680720925331116, 0.582992434501648),
|
| 201 |
+
"CD": (2.4745187759399414, -0.24800164997577667, -0.09364881366491318),
|
| 202 |
+
"OE1": (3.1685523986816406, -1.2966246604919434, -0.1717153936624527),
|
| 203 |
+
"NE2": (2.947425603866577, 0.9601329565048218, -0.6888364553451538),
|
| 204 |
+
},
|
| 205 |
+
"GLU": {
|
| 206 |
+
"N": (-1.5850872993469238, -1.337684154510498, 0.9490851163864136),
|
| 207 |
+
"CA": (-1.0560977458953857, 0.027459044009447098, 1.0306966304779053),
|
| 208 |
+
"C": (-1.7741456031799316, 0.9664392471313477, 0.09259600937366486),
|
| 209 |
+
"O": (-1.9012441635131836, 2.181349992752075, 0.402479350566864),
|
| 210 |
+
"CB": (0.4706551432609558, 0.048803869634866714, 0.8114414811134338),
|
| 211 |
+
"CG": (0.9133604764938354, -0.4219329059123993, -0.5830985307693481),
|
| 212 |
+
"CD": (2.398822069168091, -0.3097084164619446, -0.7210537791252136),
|
| 213 |
+
"OE1": (3.1389315128326416, -1.274524450302124, -0.39029765129089355),
|
| 214 |
+
"OE2": (2.9647817611694336, 0.8781346082687378, -1.1732689142227173),
|
| 215 |
+
},
|
| 216 |
+
"GLY": {
|
| 217 |
+
"N": (-1.3942985534667969, -0.39875128865242004, -0.3370324671268463),
|
| 218 |
+
"CA": (-0.39974430203437805, 0.5488945245742798, 0.15242962539196014),
|
| 219 |
+
"C": (0.9440054893493652, -0.10314033925533295, 0.19859643280506134),
|
| 220 |
+
"O": (1.3352899551391602, -0.669218122959137, 1.2541258335113525),
|
| 221 |
+
},
|
| 222 |
+
"HIS": {
|
| 223 |
+
"N": (-1.4532867670059204, -1.0689626932144165, 0.881072461605072),
|
| 224 |
+
"CA": (-1.3396095037460327, 0.24797579646110535, 0.24960045516490936),
|
| 225 |
+
"C": (-2.675257921218872, 0.6571555733680725, -0.30441102385520935),
|
| 226 |
+
"O": (-3.1311378479003906, 1.8079776763916016, -0.06785715371370316),
|
| 227 |
+
"CB": (-0.3041955828666687, 0.21721023321151733, -0.8885309100151062),
|
| 228 |
+
"CG": (1.0887513160705566, 0.028941065073013306, -0.36419469118118286),
|
| 229 |
+
"ND1": (1.840459942817688, 1.0411773920059204, 0.29804590344429016),
|
| 230 |
+
"CD2": (1.780855417251587, -1.1011489629745483, -0.3814258575439453),
|
| 231 |
+
"CE1": (2.9566943645477295, 0.4924798905849457, 0.6477115750312805),
|
| 232 |
+
"NE2": (3.0280203819274902, -0.8751969337463379, 0.26084381341934204),
|
| 233 |
+
},
|
| 234 |
+
"ILE": {
|
| 235 |
+
"N": (-0.7167549729347229, -1.5426139831542969, -0.9983330368995667),
|
| 236 |
+
"CA": (-1.0636085271835327, -0.35169270634651184, -0.21393552422523499),
|
| 237 |
+
"C": (-1.3896740674972534, 0.8142145276069641, -1.1164065599441528),
|
| 238 |
+
"O": (-1.2377792596817017, 0.7302915453910828, -2.3656840324401855),
|
| 239 |
+
"CB": (0.061667006462812424, 0.01599610224366188, 0.8057394623756409),
|
| 240 |
+
"CG1": (1.502519965171814, -0.08899776637554169, 0.24154816567897797),
|
| 241 |
+
"CG2": (-0.053174979984760284, -0.8521055579185486, 2.0702083110809326),
|
| 242 |
+
"CD1": (1.7929610013961792, 0.899773120880127, -0.8863027691841125),
|
| 243 |
+
},
|
| 244 |
+
"LEU": {
|
| 245 |
+
"N": (1.9657520055770874, -1.9763224124908447, -0.18391533195972443),
|
| 246 |
+
"CA": (1.3077669143676758, -0.6677430868148804, -0.19492436945438385),
|
| 247 |
+
"C": (1.9905058145523071, 0.24182087182998657, 0.7879968285560608),
|
| 248 |
+
"O": (2.06896710395813, -0.07880014181137085, 2.0048046112060547),
|
| 249 |
+
"CB": (-0.20306941866874695, -0.8093230128288269, 0.11243502795696259),
|
| 250 |
+
"CG": (-0.9916267395019531, 0.5234957337379456, 0.06723011285066605),
|
| 251 |
+
"CD1": (-2.4228057861328125, 0.29949337244033813, 0.573042094707489),
|
| 252 |
+
"CD2": (-1.0282856225967407, 1.1250264644622803, -1.346014380455017),
|
| 253 |
+
},
|
| 254 |
+
"LYS": {
|
| 255 |
+
"N": (2.4221372604370117, -0.6473312377929688, 0.6370573043823242),
|
| 256 |
+
"CA": (2.0314927101135254, 0.2786507308483124, -0.4298512041568756),
|
| 257 |
+
"C": (2.7168593406677246, 1.595757246017456, -0.20924785733222961),
|
| 258 |
+
"O": (3.397681713104248, 2.116427421569824, -1.1332510709762573),
|
| 259 |
+
"CB": (0.5018402934074402, 0.4873858690261841, -0.49062973260879517),
|
| 260 |
+
"CG": (-0.25062066316604614, -0.7894009947776794, -0.9055535793304443),
|
| 261 |
+
"CD": (-1.769762635231018, -0.5552700161933899, -1.040329933166504),
|
| 262 |
+
"CE": (-2.576533555984497, -1.0221366882324219, 0.18493641912937164),
|
| 263 |
+
"NZ": (-2.269151210784912, -0.24293844401836395, 1.3849012851715088),
|
| 264 |
+
},
|
| 265 |
+
"MET": {
|
| 266 |
+
"N": (1.8903918266296387, -1.5252995491027832, -0.42638593912124634),
|
| 267 |
+
"CA": (1.2630571126937866, -0.24417810142040253, -0.7626462578773499),
|
| 268 |
+
"C": (2.30391001701355, 0.8367712497711182, -0.7254616618156433),
|
| 269 |
+
"O": (2.465414524078369, 1.5928632020950317, -1.7207728624343872),
|
| 270 |
+
"CB": (0.10567972809076309, 0.10861825942993164, 0.19741646945476532),
|
| 271 |
+
"CG": (-1.0658042430877686, -0.8736631274223328, 0.08811883628368378),
|
| 272 |
+
"SD": (-2.4557132720947266, -0.3332225978374481, 1.1461700201034546),
|
| 273 |
+
"CE": (-3.265165090560913, 0.7033554911613464, -0.11588376015424728),
|
| 274 |
+
},
|
| 275 |
+
"PHE": {
|
| 276 |
+
"N": (-2.8484435081481934, -1.525790810585022, 0.01789816841483116),
|
| 277 |
+
"CA": (-1.591969609260559, -0.8545162677764893, 0.35214468836784363),
|
| 278 |
+
"C": (-1.8900631666183472, 0.45833414793014526, 1.0232222080230713),
|
| 279 |
+
"O": (-1.3424992561340332, 0.74432373046875, 2.121629476547241),
|
| 280 |
+
"CB": (-0.760358452796936, -0.6342853307723999, -0.9257160425186157),
|
| 281 |
+
"CG": (0.604112982749939, -0.07200468331575394, -0.6148118376731873),
|
| 282 |
+
"CD1": (0.8468314409255981, 1.2480632066726685, -0.7146694660186768),
|
| 283 |
+
"CD2": (1.6827683448791504, -0.9758077263832092, -0.1423054188489914),
|
| 284 |
+
"CE1": (2.1801748275756836, 1.7875733375549316, -0.3744623064994812),
|
| 285 |
+
"CE2": (2.888307809829712, -0.48277512192726135, 0.16804970800876617),
|
| 286 |
+
"CZ": (3.149812936782837, 0.9656873941421509, 0.04440271109342575),
|
| 287 |
+
},
|
| 288 |
+
"PRO": {
|
| 289 |
+
"N": (-0.836250364780426, -0.9899801015853882, 0.5561304688453674),
|
| 290 |
+
"CA": (0.32722190022468567, -0.6164458394050598, -0.25072571635246277),
|
| 291 |
+
"C": (1.6121541261672974, -1.1711241006851196, 0.31082412600517273),
|
| 292 |
+
"O": (1.6127740144729614, -2.2771971225738525, 0.9156193733215332),
|
| 293 |
+
"CB": (0.3248198926448822, 0.9028244018554688, -0.33368146419525146),
|
| 294 |
+
"CG": (-1.1425083875656128, 1.2730128765106201, -0.2590600252151489),
|
| 295 |
+
"CD": (-1.8495968580245972, 0.026575811207294464, 0.2681289613246918),
|
| 296 |
+
},
|
| 297 |
+
"SER": {
|
| 298 |
+
"N": (0.674650251865387, 1.5018702745437622, -0.5367295145988464),
|
| 299 |
+
"CA": (0.00013792862591799349, 0.4966467022895813, 0.28510504961013794),
|
| 300 |
+
"C": (0.9941009879112244, -0.5374617576599121, 0.73505038022995),
|
| 301 |
+
"O": (1.0545241832733154, -0.8683545589447021, 1.9495396614074707),
|
| 302 |
+
"CB": (-1.1279288530349731, -0.1659376323223114, -0.5160963535308838),
|
| 303 |
+
"OG": (-1.8135979175567627, -1.085249662399292, 0.28947514295578003),
|
| 304 |
+
},
|
| 305 |
+
"THR": {
|
| 306 |
+
"N": (-1.325830340385437, -1.3728225231170654, 0.6882233023643494),
|
| 307 |
+
"CA": (-0.5433306097984314, -0.16364754736423492, 0.41697052121162415),
|
| 308 |
+
"C": (-1.294381856918335, 0.7077372074127197, -0.5549946427345276),
|
| 309 |
+
"O": (-1.6939635276794434, 0.23654410243034363, -1.6540418863296509),
|
| 310 |
+
"CB": (0.853203296661377, -0.5363803505897522, -0.14109353721141815),
|
| 311 |
+
"OG1": (1.5220820903778076, -1.379003643989563, 0.7635167837142944),
|
| 312 |
+
"CG2": (1.7225933074951172, 0.7054727077484131, -0.3651331067085266),
|
| 313 |
+
},
|
| 314 |
+
"TRP": {
|
| 315 |
+
"N": (3.686030864715576, 0.7599999904632568, 0.496155709028244),
|
| 316 |
+
"CA": (2.384092092514038, 0.09079249948263168, 0.5325262546539307),
|
| 317 |
+
"C": (2.1113572120666504, -0.6121063232421875, -0.7733646035194397),
|
| 318 |
+
"O": (1.796526312828064, -1.8323148488998413, -0.7775964140892029),
|
| 319 |
+
"CB": (1.281521201133728, 1.1139036417007446, 0.8559791445732117),
|
| 320 |
+
"CG": (-0.04292375594377518, 0.44645074009895325, 1.0942792892456055),
|
| 321 |
+
"CD1": (-0.42329534888267517, -0.15470874309539795, 2.2227554321289062),
|
| 322 |
+
"CD2": (-1.1023900508880615, 0.2158389836549759, 0.11529432237148285),
|
| 323 |
+
"NE1": (-1.7030320167541504, -0.7665823101997375, 2.0595016479492188),
|
| 324 |
+
"CE2": (-2.045644998550415, -0.4881173074245453, 0.710669219493866),
|
| 325 |
+
"CE3": (-1.2173502445220947, 0.6102271676063538, -1.300106406211853),
|
| 326 |
+
"CZ2": (-3.256009340286255, -0.9164394736289978, -0.00984987337142229),
|
| 327 |
+
"CZ3": (-2.315925121307373, 0.2306906282901764, -1.9776310920715332),
|
| 328 |
+
"CH2": (-3.3817875385284424, -0.5677337646484375, -1.3032053709030151),
|
| 329 |
+
},
|
| 330 |
+
"TYR": {
|
| 331 |
+
"N": (-1.7900604009628296, -0.8409399390220642, 1.3180142641067505),
|
| 332 |
+
"CA": (-1.913882851600647, 0.23552845418453217, 0.330669641494751),
|
| 333 |
+
"C": (-3.347280740737915, 0.3588399887084961, -0.09830684959888458),
|
| 334 |
+
"O": (-3.967811346054077, -0.6449354290962219, -0.5423302054405212),
|
| 335 |
+
"CB": (-1.0093992948532104, 0.0004731413209810853, -0.8981552124023438),
|
| 336 |
+
"CG": (0.4520410895347595, 0.021162061020731926, -0.5305932760238647),
|
| 337 |
+
"CD1": (1.0992432832717896, 1.1877919435501099, -0.3579142987728119),
|
| 338 |
+
"CD2": (1.1803174018859863, -1.253401279449463, -0.31122180819511414),
|
| 339 |
+
"CE1": (2.5253450870513916, 1.1990256309509277, 0.029804613441228867),
|
| 340 |
+
"CE2": (2.471151113510132, -1.240687608718872, 0.043534230440855026),
|
| 341 |
+
"CZ": (3.180687665939331, 0.04672492295503616, 0.2214856892824173),
|
| 342 |
+
"OH": (4.523719787597656, 0.0671030730009079, 0.5877485871315002),
|
| 343 |
+
},
|
| 344 |
+
"VAL": {
|
| 345 |
+
"N": (0.5987519025802612, -1.569443702697754, -0.7379124760627747),
|
| 346 |
+
"CA": (0.6014357209205627, -0.10503966361284256, -0.6336286664009094),
|
| 347 |
+
"C": (1.8391697406768799, 0.4067850410938263, 0.06351757049560547),
|
| 348 |
+
"O": (2.3952062129974365, -0.2666190266609192, 0.9731166958808899),
|
| 349 |
+
"CB": (-0.694736897945404, 0.4259096384048462, 0.03581475466489792),
|
| 350 |
+
"CG1": (-1.9276031255722046, 0.09515828639268875, -0.8172357082366943),
|
| 351 |
+
"CG2": (-0.8938426971435547, -0.08640842139720917, 1.472349762916565),
|
| 352 |
+
},
|
| 353 |
+
"UNK": {
|
| 354 |
+
"N": (0.0, 0.0, 0.0),
|
| 355 |
+
"CA": (0.0, 0.0, 0.0),
|
| 356 |
+
"C": (0.0, 0.0, 0.0),
|
| 357 |
+
"O": (0.0, 0.0, 0.0),
|
| 358 |
+
},
|
| 359 |
+
}
|
| 360 |
+
|
| 361 |
+
# Protonated nitrogens at physiological pH (matches CHARGED_ATOMS in the
|
| 362 |
+
# opensource constants for the protein subset).
|
| 363 |
+
PROTEIN_CHARGED_ATOMS: dict[tuple[str, str], int] = {
|
| 364 |
+
("LYS", "NZ"): 1,
|
| 365 |
+
("ARG", "NH2"): 1,
|
| 366 |
+
("HIS", "ND1"): 1,
|
| 367 |
+
}
|
| 368 |
+
|
| 369 |
+
# Only the elements that appear in canonical protein heavy atoms.
|
| 370 |
+
_PROTEIN_ELEMENT_TO_ATOMIC_NUM: dict[str, int] = {"C": 6, "N": 7, "O": 8, "S": 16}
|
| 371 |
+
|
| 372 |
+
|
| 373 |
+
def _encode_atom_name(name: str) -> list[int]:
|
| 374 |
+
padded = name.ljust(4)[:4]
|
| 375 |
+
return [ord(c) - 32 if c != " " else 0 for c in padded]
|
| 376 |
+
|
| 377 |
+
|
| 378 |
+
def prepare_protein_features(sequence: str) -> dict[str, Tensor]:
|
| 379 |
+
"""Featurize a single protein sequence for ESMFold2ExperimentalModel.forward.
|
| 380 |
+
|
| 381 |
+
Returns the same keys with the same dtypes/shapes as
|
| 382 |
+
``ESMFold2InputBuilder.prepare_input(StructurePredictionInput(...))``
|
| 383 |
+
restricted to a single-chain protein with no MSA, modifications,
|
| 384 |
+
distogram conditioning, or covalent bonds. All tensors have a
|
| 385 |
+
leading batch dim of 1; the caller is responsible for moving them
|
| 386 |
+
to the model device.
|
| 387 |
+
"""
|
| 388 |
+
if not sequence:
|
| 389 |
+
raise ValueError("sequence must be non-empty")
|
| 390 |
+
|
| 391 |
+
res_3letter = [PROTEIN_1TO3.get(c, "UNK") for c in sequence]
|
| 392 |
+
L = len(sequence)
|
| 393 |
+
|
| 394 |
+
token_atom_starts: list[int] = []
|
| 395 |
+
atom_records: list[tuple[int, str, str, int, tuple[float, float, float]]] = []
|
| 396 |
+
res_type_vals: list[int] = []
|
| 397 |
+
input_id_vals: list[int] = []
|
| 398 |
+
distogram_rep_atom_idx: list[int] = []
|
| 399 |
+
|
| 400 |
+
atom_cursor = 0
|
| 401 |
+
for t_idx, (letter, res_3) in enumerate(zip(sequence, res_3letter)):
|
| 402 |
+
atom_names = PROTEIN_HEAVY_ATOMS[res_3]
|
| 403 |
+
res_type = PROTEIN_RESIDUE_TO_RES_TYPE.get(res_3, PROTEIN_UNK_RES_TYPE)
|
| 404 |
+
input_id = ESM_PROTEIN_VOCAB.get(letter, ESM_PROTEIN_VOCAB["X"])
|
| 405 |
+
|
| 406 |
+
token_atom_starts.append(atom_cursor)
|
| 407 |
+
for name in atom_names:
|
| 408 |
+
charge = PROTEIN_CHARGED_ATOMS.get((res_3, name), 0)
|
| 409 |
+
element = name[0] # protein heavy atoms are all single-letter C/N/O/S
|
| 410 |
+
ref_pos = PROTEIN_REF_POS[res_3][name]
|
| 411 |
+
atom_records.append((t_idx, name, element, charge, ref_pos))
|
| 412 |
+
atom_cursor += 1
|
| 413 |
+
|
| 414 |
+
rep_name = "CB" if "CB" in atom_names else "CA"
|
| 415 |
+
distogram_rep_atom_idx.append(
|
| 416 |
+
token_atom_starts[t_idx] + atom_names.index(rep_name)
|
| 417 |
+
)
|
| 418 |
+
|
| 419 |
+
res_type_vals.append(res_type)
|
| 420 |
+
input_id_vals.append(input_id)
|
| 421 |
+
|
| 422 |
+
n_real_atoms = len(atom_records)
|
| 423 |
+
n_atoms = math.ceil(n_real_atoms / 32) * 32 if n_real_atoms > 0 else 32
|
| 424 |
+
|
| 425 |
+
ref_pos = torch.zeros(n_atoms, 3, dtype=torch.float32)
|
| 426 |
+
ref_element = torch.zeros(n_atoms, dtype=torch.int64)
|
| 427 |
+
ref_charge = torch.zeros(n_atoms, dtype=torch.int8)
|
| 428 |
+
ref_atom_name_chars = torch.zeros(n_atoms, 4, dtype=torch.int64)
|
| 429 |
+
ref_space_uid = torch.zeros(n_atoms, dtype=torch.int64)
|
| 430 |
+
atom_attention_mask = torch.zeros(n_atoms, dtype=torch.bool)
|
| 431 |
+
atom_to_token = torch.zeros(n_atoms, dtype=torch.int64)
|
| 432 |
+
|
| 433 |
+
for i, (t_idx, name, element, charge, pos) in enumerate(atom_records):
|
| 434 |
+
ref_pos[i] = torch.tensor(pos, dtype=torch.float32)
|
| 435 |
+
ref_element[i] = _PROTEIN_ELEMENT_TO_ATOMIC_NUM[element]
|
| 436 |
+
ref_charge[i] = charge
|
| 437 |
+
ref_atom_name_chars[i] = torch.tensor(
|
| 438 |
+
_encode_atom_name(name), dtype=torch.int64
|
| 439 |
+
)
|
| 440 |
+
ref_space_uid[i] = t_idx
|
| 441 |
+
atom_attention_mask[i] = True
|
| 442 |
+
atom_to_token[i] = t_idx
|
| 443 |
+
|
| 444 |
+
token_index = torch.arange(L, dtype=torch.int64)
|
| 445 |
+
residue_index = torch.arange(L, dtype=torch.int64)
|
| 446 |
+
asym_id = torch.zeros(L, dtype=torch.int64)
|
| 447 |
+
sym_id = torch.zeros(L, dtype=torch.int64)
|
| 448 |
+
entity_id = torch.ones(L, dtype=torch.int64)
|
| 449 |
+
mol_type = torch.full((L,), MOL_TYPE_PROTEIN, dtype=torch.int64)
|
| 450 |
+
res_type = torch.tensor(res_type_vals, dtype=torch.int64)
|
| 451 |
+
input_ids = torch.tensor(input_id_vals, dtype=torch.int64)
|
| 452 |
+
token_bonds = torch.zeros(L, L, 1, dtype=torch.float32)
|
| 453 |
+
token_attention_mask = torch.ones(L, dtype=torch.bool)
|
| 454 |
+
distogram_atom_idx = torch.tensor(distogram_rep_atom_idx, dtype=torch.int64)
|
| 455 |
+
|
| 456 |
+
# Single-sequence MSA: depth 1, row 0 is the sequence itself.
|
| 457 |
+
msa = res_type.unsqueeze(0)
|
| 458 |
+
msa_attention_mask = torch.ones(1, L, dtype=torch.bool)
|
| 459 |
+
has_deletion = torch.zeros(1, L, dtype=torch.bool)
|
| 460 |
+
deletion_value = torch.zeros(1, L, dtype=torch.float32)
|
| 461 |
+
deletion_mean = torch.zeros(L, dtype=torch.float32)
|
| 462 |
+
|
| 463 |
+
features = {
|
| 464 |
+
"token_index": token_index,
|
| 465 |
+
"residue_index": residue_index,
|
| 466 |
+
"asym_id": asym_id,
|
| 467 |
+
"sym_id": sym_id,
|
| 468 |
+
"entity_id": entity_id,
|
| 469 |
+
"mol_type": mol_type,
|
| 470 |
+
"res_type": res_type,
|
| 471 |
+
"input_ids": input_ids,
|
| 472 |
+
"token_bonds": token_bonds,
|
| 473 |
+
"token_attention_mask": token_attention_mask,
|
| 474 |
+
"ref_pos": ref_pos,
|
| 475 |
+
"ref_element": ref_element,
|
| 476 |
+
"ref_charge": ref_charge,
|
| 477 |
+
"ref_atom_name_chars": ref_atom_name_chars,
|
| 478 |
+
"ref_space_uid": ref_space_uid,
|
| 479 |
+
"atom_attention_mask": atom_attention_mask,
|
| 480 |
+
"atom_to_token": atom_to_token,
|
| 481 |
+
"distogram_atom_idx": distogram_atom_idx,
|
| 482 |
+
"msa": msa,
|
| 483 |
+
"msa_attention_mask": msa_attention_mask,
|
| 484 |
+
"has_deletion": has_deletion,
|
| 485 |
+
"deletion_value": deletion_value,
|
| 486 |
+
"deletion_mean": deletion_mean,
|
| 487 |
+
}
|
| 488 |
+
return {k: v.unsqueeze(0) for k, v in features.items()}
|