


Stage Harbor release files 6001-6500
Browse filesThis view is limited to 50 files because it contains too many changes. See raw diff
- tasks/tasksmith-1c108f674e97/tests/source/docs/source/kernels_hub.md +96 -0
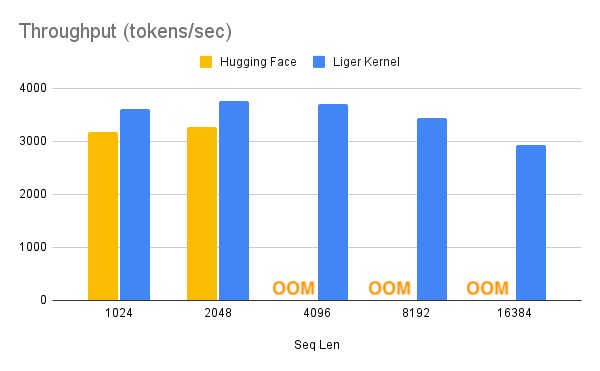
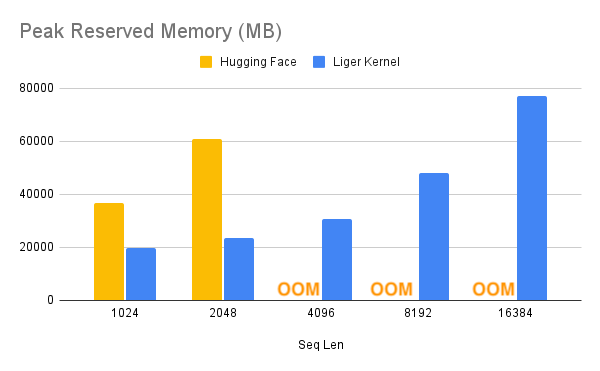
- tasks/tasksmith-1c108f674e97/tests/source/docs/source/kto_trainer.md +144 -0
- tasks/tasksmith-1c108f674e97/tests/source/docs/source/liger_kernel_integration.md +78 -0
- tasks/tasksmith-1c108f674e97/tests/source/docs/source/lora_without_regret.md +346 -0
- tasks/tasksmith-1c108f674e97/tests/source/docs/source/merge_model_callback.md +3 -0
- tasks/tasksmith-1c108f674e97/tests/source/docs/source/minillm_trainer.md +67 -0
- tasks/tasksmith-1c108f674e97/tests/source/docs/source/nash_md_trainer.md +140 -0
- tasks/tasksmith-1c108f674e97/tests/source/docs/source/nemo_gym.md +293 -0
- tasks/tasksmith-1c108f674e97/tests/source/docs/source/online_dpo_trainer.md +206 -0
- tasks/tasksmith-1c108f674e97/tests/source/docs/source/openenv.md +659 -0
- tasks/tasksmith-1c108f674e97/tests/source/docs/source/orpo_trainer.md +131 -0
- tasks/tasksmith-1c108f674e97/tests/source/docs/source/paper_index.md +1825 -0
- tasks/tasksmith-1c108f674e97/tests/source/docs/source/papo_trainer.md +20 -0
- tasks/tasksmith-1c108f674e97/tests/source/docs/source/peft_integration.md +822 -0
- tasks/tasksmith-1c108f674e97/tests/source/docs/source/ppo_trainer.md +252 -0
- tasks/tasksmith-1c108f674e97/tests/source/docs/source/prm_trainer.md +122 -0
- tasks/tasksmith-1c108f674e97/tests/source/docs/source/ptt_integration.md +193 -0
- tasks/tasksmith-1c108f674e97/tests/source/docs/source/quickstart.md +139 -0
- tasks/tasksmith-1c108f674e97/tests/source/docs/source/rapidfire_integration.md +473 -0
- tasks/tasksmith-1c108f674e97/tests/source/docs/source/reducing_memory_usage.md +360 -0
- tasks/tasksmith-1c108f674e97/tests/source/docs/source/reward_trainer.md +234 -0
- tasks/tasksmith-1c108f674e97/tests/source/docs/source/rewards.md +19 -0
- tasks/tasksmith-1c108f674e97/tests/source/docs/source/rloo_trainer.md +642 -0
- tasks/tasksmith-1c108f674e97/tests/source/docs/source/script_utils.md +24 -0
- tasks/tasksmith-1c108f674e97/tests/source/docs/source/sdft_trainer.md +104 -0
- tasks/tasksmith-1c108f674e97/tests/source/docs/source/sdpo_trainer.md +108 -0
- tasks/tasksmith-1c108f674e97/tests/source/docs/source/sft_trainer.md +349 -0
- tasks/tasksmith-1c108f674e97/tests/source/docs/source/speeding_up_training.md +204 -0
- tasks/tasksmith-1c108f674e97/tests/source/docs/source/ssd_trainer.md +111 -0
- tasks/tasksmith-1c108f674e97/tests/source/docs/source/tpo_trainer.md +135 -0
- tasks/tasksmith-1c108f674e97/tests/source/docs/source/trackio_integration.md +67 -0
- tasks/tasksmith-1c108f674e97/tests/source/docs/source/unsloth_integration.md +125 -0
- tasks/tasksmith-1c108f674e97/tests/source/docs/source/use_model.md +58 -0
- tasks/tasksmith-1c108f674e97/tests/source/docs/source/vllm_integration.md +430 -0
- tasks/tasksmith-1c108f674e97/tests/source/docs/source/xpo_trainer.md +145 -0
- tasks/tasksmith-1c108f674e97/tests/source/examples/README.md +3 -0
- tasks/tasksmith-1c108f674e97/tests/source/examples/accelerate_configs/alst_ulysses_4gpu.yaml +45 -0
- tasks/tasksmith-1c108f674e97/tests/source/examples/accelerate_configs/context_parallel_2gpu.yaml +30 -0
- tasks/tasksmith-1c108f674e97/tests/source/examples/accelerate_configs/deepspeed_zero1.yaml +20 -0
- tasks/tasksmith-1c108f674e97/tests/source/examples/accelerate_configs/deepspeed_zero2.yaml +21 -0
- tasks/tasksmith-1c108f674e97/tests/source/examples/accelerate_configs/deepspeed_zero3.yaml +22 -0
- tasks/tasksmith-1c108f674e97/tests/source/examples/accelerate_configs/fsdp1.yaml +28 -0
- tasks/tasksmith-1c108f674e97/tests/source/examples/accelerate_configs/fsdp2.yaml +25 -0
- tasks/tasksmith-1c108f674e97/tests/source/examples/accelerate_configs/multi_gpu.yaml +16 -0
- tasks/tasksmith-1c108f674e97/tests/source/examples/accelerate_configs/single_gpu.yaml +16 -0
- tasks/tasksmith-1c108f674e97/tests/source/examples/cli_configs/example_config.yaml +18 -0
- tasks/tasksmith-1c108f674e97/tests/source/examples/datasets/deepmath_103k.py +98 -0
- tasks/tasksmith-1c108f674e97/tests/source/examples/datasets/hh-rlhf-helpful-base.py +132 -0
- tasks/tasksmith-1c108f674e97/tests/source/examples/datasets/llava_instruct_mix.py +118 -0
- tasks/tasksmith-1c108f674e97/tests/source/examples/datasets/lm-human-preferences-descriptiveness.py +119 -0
tasks/tasksmith-1c108f674e97/tests/source/docs/source/kernels_hub.md
ADDED
|
@@ -0,0 +1,96 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Kernels Hub Integration and Usage
|
| 2 |
+
|
| 3 |
+
<img src="https://github.com/user-attachments/assets/4b5175f3-1d60-455b-8664-43b2495ee1c3" width="450" height="450" alt="kernel-builder logo">
|
| 4 |
+
|
| 5 |
+
The [`kernels`](https://huggingface.co/blog/hello-hf-kernels#get-started-and-next-steps) library allows optimized compute kernels to be loaded directly from the Hub.
|
| 6 |
+
You can find `kernels` in [dedicated orgs](https://huggingface.co/kernels-community) or by searching for the [`kernel` tag](https://huggingface.co/models?other=kernel) within the Hub.
|
| 7 |
+
|
| 8 |
+
Kernels are **optimized code pieces** that help in model development, training, and inference. Here, we’ll focus on their **integration with TRL**, but check out the above resources to learn more about them.
|
| 9 |
+
|
| 10 |
+
## Installation
|
| 11 |
+
|
| 12 |
+
To use kernels with TRL, you'd need to install the library in your Python environment:
|
| 13 |
+
|
| 14 |
+
```bash
|
| 15 |
+
pip install kernels
|
| 16 |
+
```
|
| 17 |
+
|
| 18 |
+
## Using Kernels from the Hub in TRL
|
| 19 |
+
|
| 20 |
+
Kernels can directly replace attention implementations, removing the need to manually compile attention backends like Flash Attention and boosting training speed just by pulling the respective attention kernel from the Hub.
|
| 21 |
+
|
| 22 |
+
You can specify a kernel when loading a model:
|
| 23 |
+
|
| 24 |
+
|
| 25 |
+
```python
|
| 26 |
+
from transformers import AutoModelForCausalLM
|
| 27 |
+
|
| 28 |
+
model = AutoModelForCausalLM.from_pretrained(
|
| 29 |
+
"your-model-name",
|
| 30 |
+
attn_implementation="kernels-community/flash-attn2" # other options: kernels-community/vllm-flash-attn3, kernels-community/paged-attention
|
| 31 |
+
)
|
| 32 |
+
```
|
| 33 |
+
|
| 34 |
+
Or when running a TRL training script:
|
| 35 |
+
|
| 36 |
+
```bash
|
| 37 |
+
python sft.py ... --attn_implementation kernels-community/flash-attn2
|
| 38 |
+
```
|
| 39 |
+
|
| 40 |
+
Or using the TRL CLI:
|
| 41 |
+
|
| 42 |
+
```bash
|
| 43 |
+
trl sft ... --attn_implementation kernels-community/flash-attn2
|
| 44 |
+
```
|
| 45 |
+
|
| 46 |
+
> [!TIP]
|
| 47 |
+
> Now you can leverage faster attention backends with a pre-optimized kernel for your hardware configuration from the Hub, speeding up both development and training.
|
| 48 |
+
|
| 49 |
+
## Comparing Attention Implementations
|
| 50 |
+
|
| 51 |
+
We evaluated various attention implementations available in transformers, along with different kernel backends, using **TRL** and **SFT**.
|
| 52 |
+
The experiments were run on a single **H100 GPU** with **CUDA 12.9**, leveraging **Qwen3-8B** with a **batch size of 8**, **gradient accumulation of 1**, and **bfloat16** precision.
|
| 53 |
+
Keep in mind that the results shown here are specific to this setup and may vary with different training configurations.
|
| 54 |
+
|
| 55 |
+
The following figure illustrates both **latency** (time per training step) and **peak allocated memory** for the different attention implementations and kernel backends.
|
| 56 |
+
Kernel-based implementations perform on par with custom-installed attention, and increasing the model’s `max_length` further enhances performance. Memory consumption is similar across all implementations, showing no significant differences. We get the same performance but with less friction, as described in [the following section](#flash-attention-vs-hub-kernels).
|
| 57 |
+
|
| 58 |
+
<div class="flex justify-center">
|
| 59 |
+
<img src="https://huggingface.co/datasets/trl-lib/documentation-images/resolve/main/kernels_guide_latency.png" alt="Latency and Memory Usage" width="45%"/>
|
| 60 |
+
<img src="https://huggingface.co/datasets/trl-lib/documentation-images/resolve/main/kernels_guide_peak_allocated_memory.png" alt="Latency and Memory Usage" width="45%"/>
|
| 61 |
+
</div>
|
| 62 |
+
|
| 63 |
+
## Flash Attention vs. Hub Kernels
|
| 64 |
+
|
| 65 |
+
Building Flash Attention from source can be time-consuming, often taking anywhere from several minutes to hours, depending on your hardware, CUDA/PyTorch configuration, and whether precompiled wheels are available.
|
| 66 |
+
|
| 67 |
+
In contrast, **Hugging Face Kernels** provide a much faster and more reliable workflow. Developers don’t need to worry about complex setups—everything is handled automatically. In our benchmarks, kernels were ready to use in about **2.5 seconds**, with no compilation required. This allows you to start training almost instantly, significantly accelerating development. Simply specify the desired version, and `kernels` takes care of the rest.
|
| 68 |
+
|
| 69 |
+
## Combining FlashAttention Kernels with Liger Kernels
|
| 70 |
+
|
| 71 |
+
You can combine **FlashAttention kernels** with **Liger kernels** for additional TRL performance improvements.
|
| 72 |
+
|
| 73 |
+
First, install the Liger kernel dependency:
|
| 74 |
+
|
| 75 |
+
```bash
|
| 76 |
+
pip install liger-kernel
|
| 77 |
+
```
|
| 78 |
+
|
| 79 |
+
Then, combine both in your code:
|
| 80 |
+
|
| 81 |
+
```python
|
| 82 |
+
from transformers import AutoModelForCausalLM
|
| 83 |
+
from trl import SFTConfig
|
| 84 |
+
|
| 85 |
+
model = AutoModelForCausalLM.from_pretrained(
|
| 86 |
+
"your-model-name",
|
| 87 |
+
attn_implementation="kernels-community/flash-attn2" # choose the desired FlashAttention variant
|
| 88 |
+
)
|
| 89 |
+
|
| 90 |
+
training_args = SFTConfig(
|
| 91 |
+
use_liger_kernel=True,
|
| 92 |
+
# ... other TRL training args
|
| 93 |
+
)
|
| 94 |
+
```
|
| 95 |
+
|
| 96 |
+
Learn more about the [Liger Kernel Integration](./liger_kernel_integration).
|
tasks/tasksmith-1c108f674e97/tests/source/docs/source/kto_trainer.md
ADDED
|
@@ -0,0 +1,144 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# KTO Trainer
|
| 2 |
+
|
| 3 |
+
[](https://huggingface.co/models?other=kto,trl)
|
| 4 |
+
|
| 5 |
+
> [!WARNING]
|
| 6 |
+
> As of TRL v1.0, `KTOTrainer` and `KTOConfig` have been moved to the `trl.experimental.kto` module.
|
| 7 |
+
> KTO API is experimental and may change at any time.
|
| 8 |
+
> Promoting KTO back into the stable API is a high-priority task: KTO is slated for refactoring to align with the standard core trainer architecture.
|
| 9 |
+
|
| 10 |
+
## Overview
|
| 11 |
+
|
| 12 |
+
Kahneman-Tversky Optimization (KTO) was introduced in [KTO: Model Alignment as Prospect Theoretic Optimization](https://huggingface.co/papers/2402.01306) by [Kawin Ethayarajh](https://huggingface.co/kawine), [Winnie Xu](https://huggingface.co/xwinxu), [Niklas Muennighoff](https://huggingface.co/Muennighoff), Dan Jurafsky, [Douwe Kiela](https://huggingface.co/douwekiela).
|
| 13 |
+
|
| 14 |
+
The abstract from the paper is the following:
|
| 15 |
+
|
| 16 |
+
> Kahneman & Tversky's prospect theory tells us that humans perceive random variables in a biased but well-defined manner; for example, humans are famously loss-averse. We show that objectives for aligning LLMs with human feedback implicitly incorporate many of these biases -- the success of these objectives (e.g., DPO) over cross-entropy minimization can partly be ascribed to them being human-aware loss functions (HALOs). However, the utility functions these methods attribute to humans still differ from those in the prospect theory literature. Using a Kahneman-Tversky model of human utility, we propose a HALO that directly maximizes the utility of generations instead of maximizing the log-likelihood of preferences, as current methods do. We call this approach Kahneman-Tversky Optimization (KTO), and it matches or exceeds the performance of preference-based methods at scales from 1B to 30B. Crucially, KTO does not need preferences -- only a binary signal of whether an output is desirable or undesirable for a given input. This makes it far easier to use in the real world, where preference data is scarce and expensive.
|
| 17 |
+
|
| 18 |
+
The official code can be found in [ContextualAI/HALOs](https://github.com/ContextualAI/HALOs).
|
| 19 |
+
|
| 20 |
+
This post-training method was contributed by [Kashif Rasul](https://huggingface.co/kashif), [Younes Belkada](https://huggingface.co/ybelkada), [Lewis Tunstall](https://huggingface.co/lewtun) and Pablo Vicente.
|
| 21 |
+
|
| 22 |
+
## Quick start
|
| 23 |
+
|
| 24 |
+
This example demonstrates how to train a model using the KTO method. We use the [Qwen 0.5B model](https://huggingface.co/Qwen/Qwen2-0.5B-Instruct) as the base model. We use the preference data from the [KTO Mix 14k](https://huggingface.co/datasets/trl-lib/kto-mix-14k). You can view the data in the dataset here:
|
| 25 |
+
|
| 26 |
+
<iframe
|
| 27 |
+
src="https://huggingface.co/datasets/trl-lib/kto-mix-14k/embed/viewer/default/train?row=0"
|
| 28 |
+
frameborder="0"
|
| 29 |
+
width="100%"
|
| 30 |
+
height="560px"
|
| 31 |
+
></iframe>
|
| 32 |
+
|
| 33 |
+
Below is the script to train the model:
|
| 34 |
+
|
| 35 |
+
```python
|
| 36 |
+
# train_kto.py
|
| 37 |
+
from datasets import load_dataset
|
| 38 |
+
from trl.experimental.kto import KTOConfig, KTOTrainer
|
| 39 |
+
from transformers import AutoModelForCausalLM, AutoTokenizer
|
| 40 |
+
|
| 41 |
+
model = AutoModelForCausalLM.from_pretrained("Qwen/Qwen2-0.5B-Instruct")
|
| 42 |
+
tokenizer = AutoTokenizer.from_pretrained("Qwen/Qwen2-0.5B-Instruct")
|
| 43 |
+
train_dataset = load_dataset("trl-lib/kto-mix-14k", split="train")
|
| 44 |
+
|
| 45 |
+
training_args = KTOConfig(output_dir="Qwen2-0.5B-KTO")
|
| 46 |
+
trainer = KTOTrainer(model=model, args=training_args, processing_class=tokenizer, train_dataset=train_dataset)
|
| 47 |
+
trainer.train()
|
| 48 |
+
```
|
| 49 |
+
|
| 50 |
+
Execute the script using the following command:
|
| 51 |
+
|
| 52 |
+
```bash
|
| 53 |
+
accelerate launch train_kto.py
|
| 54 |
+
```
|
| 55 |
+
|
| 56 |
+
Distributed across 8 x H100 GPUs, the training takes approximately 30 minutes. You can verify the training progress by checking the reward graph. An increasing trend in the reward margin indicates that the model is improving and generating better responses over time.
|
| 57 |
+
|
| 58 |
+

|
| 59 |
+
|
| 60 |
+
To see how the [trained model](https://huggingface.co/trl-lib/Qwen2-0.5B-KTO) performs, you can use the [Transformers Chat CLI](https://huggingface.co/docs/transformers/quicktour#chat-with-text-generation-models).
|
| 61 |
+
|
| 62 |
+
<pre><code>$ transformers chat trl-lib/Qwen2-0.5B-KTO
|
| 63 |
+
<strong><span style="color: red;"><quentin_gallouedec>:</span></strong>
|
| 64 |
+
What is the best programming language?
|
| 65 |
+
|
| 66 |
+
<strong><span style="color: blue;"><trl-lib/Qwen2-0.5B-KTO>:</span></strong>
|
| 67 |
+
The best programming language can vary depending on individual preferences, industry-specific requirements, technical skills, and familiarity with the specific use case or task. Here are some widely-used programming languages that have been noted as popular and widely used:
|
| 68 |
+
|
| 69 |
+
Here are some other factors to consider when choosing a programming language for a project:
|
| 70 |
+
|
| 71 |
+
<strong><span style="color: green;">1</span> JavaScript</strong>: JavaScript is at the heart of the web and can be used for building web applications, APIs, and interactive front-end applications like frameworks like React and Angular. It's similar to C, C++, and F# in syntax structure and is accessible and easy to learn, making it a popular choice for beginners and professionals alike.
|
| 72 |
+
<strong><span style="color: green;">2</span> Java</strong>: Known for its object-oriented programming (OOP) and support for Java 8 and .NET, Java is used for developing enterprise-level software applications, high-performance games, as well as mobile apps, game development, and desktop applications.
|
| 73 |
+
<strong><span style="color: green;">3</span> C++</strong>: Known for its flexibility and scalability, C++ offers comprehensive object-oriented programming and is a popular choice for high-performance computing and other technical fields. It's a powerful platform for building real-world applications and games at scale.
|
| 74 |
+
<strong><span style="color: green;">4</span> Python</strong>: Developed by Guido van Rossum in 1991, Python is a high-level, interpreted, and dynamically typed language known for its simplicity, readability, and versatility.
|
| 75 |
+
</code></pre>
|
| 76 |
+
|
| 77 |
+
## Expected dataset format
|
| 78 |
+
|
| 79 |
+
KTO requires an [unpaired preference dataset](dataset_formats#unpaired-preference). Alternatively, you can provide a *paired* preference dataset (also known simply as a *preference dataset*). In this case, the trainer will automatically convert it to an unpaired format by separating the chosen and rejected responses, assigning `label = True` to the chosen completions and `label = False` to the rejected ones.
|
| 80 |
+
|
| 81 |
+
The [`experimental.kto.KTOTrainer`] supports both [conversational](dataset_formats#conversational) and [standard](dataset_formats#standard) dataset formats. When provided with a conversational dataset, the trainer will automatically apply the chat template to the dataset.
|
| 82 |
+
|
| 83 |
+
In theory, the dataset should contain at least one chosen and one rejected completion. However, some users have successfully run KTO using *only* chosen or only rejected data. If using only rejected data, it is advisable to adopt a conservative learning rate.
|
| 84 |
+
|
| 85 |
+
## Example script
|
| 86 |
+
|
| 87 |
+
We provide an example script to train a model using the KTO method. The script is available in [`trl/scripts/kto.py`](https://github.com/huggingface/trl/blob/main/trl/scripts/kto.py)
|
| 88 |
+
|
| 89 |
+
To test the KTO script with the [Qwen2 0.5B model](https://huggingface.co/Qwen/Qwen2-0.5B-Instruct) on the [UltraFeedback dataset](https://huggingface.co/datasets/trl-lib/kto-mix-14k), run the following command:
|
| 90 |
+
|
| 91 |
+
```bash
|
| 92 |
+
accelerate launch trl/scripts/kto.py \
|
| 93 |
+
--model_name_or_path Qwen/Qwen2-0.5B-Instruct \
|
| 94 |
+
--dataset_name trl-lib/kto-mix-14k \
|
| 95 |
+
--num_train_epochs 1 \
|
| 96 |
+
--output_dir Qwen2-0.5B-KTO
|
| 97 |
+
```
|
| 98 |
+
|
| 99 |
+
## Usage tips
|
| 100 |
+
|
| 101 |
+
### For Mixture of Experts Models: Enabling the auxiliary loss
|
| 102 |
+
|
| 103 |
+
MOEs are the most efficient if the load is about equally distributed between experts.
|
| 104 |
+
To ensure that we train MOEs similarly during preference-tuning, it is beneficial to add the auxiliary loss from the load balancer to the final loss.
|
| 105 |
+
|
| 106 |
+
This option is enabled by setting `output_router_logits=True` in the model config (e.g. [`~transformers.MixtralConfig`]).
|
| 107 |
+
To scale how much the auxiliary loss contributes to the total loss, use the hyperparameter `router_aux_loss_coef=...` (default: `0.001`) in the model config.
|
| 108 |
+
|
| 109 |
+
### Batch size recommendations
|
| 110 |
+
|
| 111 |
+
Use a per-step batch size that is at least 4, and an effective batch size between 16 and 128. Even if your effective batch size is large, if your per-step batch size is poor, then the KL estimate in KTO will be poor.
|
| 112 |
+
|
| 113 |
+
### Learning rate recommendations
|
| 114 |
+
|
| 115 |
+
Each choice of `beta` has a maximum learning rate it can tolerate before learning performance degrades. For the default setting of `beta = 0.1`, the learning rate should typically not exceed `1e-6` for most models. As `beta` decreases, the learning rate should also be reduced accordingly. In general, we strongly recommend keeping the learning rate between `5e-7` and `5e-6`. Even with small datasets, we advise against using a learning rate outside this range. Instead, opt for more epochs to achieve better results.
|
| 116 |
+
|
| 117 |
+
### Imbalanced data
|
| 118 |
+
|
| 119 |
+
The `desirable_weight` and `undesirable_weight` of the [`experimental.kto.KTOConfig`] refer to the weights placed on the losses for desirable/positive and undesirable/negative examples.
|
| 120 |
+
By default, they are both 1. However, if you have more of one or the other, then you should upweight the less common type such that the ratio of (`desirable_weight` \\(\times\\) number of positives) to (`undesirable_weight` \\(\times\\) number of negatives) is in the range 1:1 to 4:3.
|
| 121 |
+
|
| 122 |
+
## Logged metrics
|
| 123 |
+
|
| 124 |
+
While training and evaluating, we record the following reward metrics:
|
| 125 |
+
|
| 126 |
+
- `rewards/chosen_sum`: the sum of log probabilities of the policy model for the chosen responses scaled by beta
|
| 127 |
+
- `rewards/rejected_sum`: the sum of log probabilities of the policy model for the rejected responses scaled by beta
|
| 128 |
+
- `logps/chosen_sum`: the sum of log probabilities of the chosen completions
|
| 129 |
+
- `logps/rejected_sum`: the sum of log probabilities of the rejected completions
|
| 130 |
+
- `logits/chosen_sum`: the sum of logits of the chosen completions
|
| 131 |
+
- `logits/rejected_sum`: the sum of logits of the rejected completions
|
| 132 |
+
- `count/chosen`: the count of chosen samples in a batch
|
| 133 |
+
- `count/rejected`: the count of rejected samples in a batch
|
| 134 |
+
|
| 135 |
+
## KTOTrainer
|
| 136 |
+
|
| 137 |
+
[[autodoc]] experimental.kto.KTOTrainer
|
| 138 |
+
- train
|
| 139 |
+
- save_model
|
| 140 |
+
- push_to_hub
|
| 141 |
+
|
| 142 |
+
## KTOConfig
|
| 143 |
+
|
| 144 |
+
[[autodoc]] experimental.kto.KTOConfig
|
tasks/tasksmith-1c108f674e97/tests/source/docs/source/liger_kernel_integration.md
ADDED
|
@@ -0,0 +1,78 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Liger Kernel Integration
|
| 2 |
+
|
| 3 |
+
[Liger Kernel](https://github.com/linkedin/Liger-Kernel) is a collection of Triton kernels designed specifically for LLM training. It can effectively increase multi-GPU training throughput by 20% and reduce memory usage by 60%. That way, we can **4x** our context length, as described in the benchmark below. They have implemented Hugging Face compatible `RMSNorm`, `RoPE`, `SwiGLU`, `CrossEntropy`, `FusedLinearCrossEntropy`, with more to come. The kernel works out of the box with [FlashAttention](https://github.com/Dao-AILab/flash-attention), [PyTorch FSDP](https://pytorch.org/tutorials/intermediate/FSDP_tutorial.html), and [Microsoft DeepSpeed](https://github.com/microsoft/DeepSpeed).
|
| 4 |
+
|
| 5 |
+
With this memory reduction, you can potentially turn off `cpu_offloading` or gradient checkpointing to further boost the performance.
|
| 6 |
+
|
| 7 |
+
| Speed Up | Memory Reduction |
|
| 8 |
+
| --- | --- |
|
| 9 |
+
|  |  |
|
| 10 |
+
|
| 11 |
+
## Supported Trainers
|
| 12 |
+
|
| 13 |
+
Liger Kernel is supported in the following TRL trainers:
|
| 14 |
+
- **SFT** (Supervised Fine-Tuning)
|
| 15 |
+
- **DPO** (Direct Preference Optimization)
|
| 16 |
+
- **GRPO** (Group Relative Policy Optimization)
|
| 17 |
+
- **KTO** (Kahneman-Tversky Optimization)
|
| 18 |
+
- **GKD** (Generalized Knowledge Distillation)
|
| 19 |
+
|
| 20 |
+
## Usage
|
| 21 |
+
|
| 22 |
+
1. First, install Liger Kernel:
|
| 23 |
+
|
| 24 |
+
```bash
|
| 25 |
+
pip install liger-kernel
|
| 26 |
+
```
|
| 27 |
+
|
| 28 |
+
2. Once installed, set `use_liger_kernel=True` in your trainer config. No other changes are needed!
|
| 29 |
+
|
| 30 |
+
<hfoptions id="liger">
|
| 31 |
+
<hfoption id="SFT">
|
| 32 |
+
|
| 33 |
+
```python
|
| 34 |
+
from trl import SFTConfig
|
| 35 |
+
|
| 36 |
+
training_args = SFTConfig(..., use_liger_kernel=True)
|
| 37 |
+
```
|
| 38 |
+
|
| 39 |
+
</hfoption>
|
| 40 |
+
<hfoption id="DPO">
|
| 41 |
+
|
| 42 |
+
```python
|
| 43 |
+
from trl import DPOConfig
|
| 44 |
+
|
| 45 |
+
training_args = DPOConfig(..., use_liger_kernel=True)
|
| 46 |
+
```
|
| 47 |
+
|
| 48 |
+
</hfoption>
|
| 49 |
+
<hfoption id="GRPO">
|
| 50 |
+
|
| 51 |
+
```python
|
| 52 |
+
from trl import GRPOConfig
|
| 53 |
+
|
| 54 |
+
training_args = GRPOConfig(..., use_liger_kernel=True)
|
| 55 |
+
```
|
| 56 |
+
|
| 57 |
+
</hfoption>
|
| 58 |
+
<hfoption id="KTO">
|
| 59 |
+
|
| 60 |
+
```python
|
| 61 |
+
from trl import KTOConfig
|
| 62 |
+
|
| 63 |
+
training_args = KTOConfig(..., use_liger_kernel=True)
|
| 64 |
+
```
|
| 65 |
+
|
| 66 |
+
</hfoption>
|
| 67 |
+
<hfoption id="GKD">
|
| 68 |
+
|
| 69 |
+
```python
|
| 70 |
+
from trl.experimental.gkd import GKDConfig
|
| 71 |
+
|
| 72 |
+
training_args = GKDConfig(..., use_liger_kernel=True)
|
| 73 |
+
```
|
| 74 |
+
|
| 75 |
+
</hfoption>
|
| 76 |
+
</hfoptions>
|
| 77 |
+
|
| 78 |
+
To learn more about Liger-Kernel, visit their [official repository](https://github.com/linkedin/Liger-Kernel/).
|
tasks/tasksmith-1c108f674e97/tests/source/docs/source/lora_without_regret.md
ADDED
|
@@ -0,0 +1,346 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# LoRA Without Regret
|
| 2 |
+
|
| 3 |
+
Recent research from the team at [Thinking Machines Lab](https://thinkingmachines.ai/blog/lora/) (Schulman et al., 2025) shows that **LoRA can match full fine-tuning performance** when configured correctly, while using only ~67% of the compute. These findings are exciting to TRL users because they're straightforward to implement and can improve model performance on smaller budgets.
|
| 4 |
+
|
| 5 |
+
This guide provides simple instructions to reproduce the results of the blog post in TRL.
|
| 6 |
+
|
| 7 |
+
> [!TIP]
|
| 8 |
+
> It is recommended to read the blog post before following this guide, or to consult both resources in parallel for best results.
|
| 9 |
+
|
| 10 |
+
## Benefits of LoRA over full fine-tuning
|
| 11 |
+
|
| 12 |
+
First of all, let's remind ourselves of the benefits of [LoRA over full fine-tuning](https://huggingface.co/docs/trl/en/peft_integration).
|
| 13 |
+
|
| 14 |
+
LoRA adds adapter layers on top of the base model, which contains significantly fewer parameters than the base model itself. This design reduces GPU memory requirements and enables more efficient training. As described in the [blog](https://thinkingmachines.ai/blog/lora/), this approach was originally thought to involve a performance trade-off, although careful configuration can overcome this trade-off and match full fine-tuning performance.
|
| 15 |
+
|
| 16 |
+
## Examples with TRL
|
| 17 |
+
|
| 18 |
+
Let's implement and train LoRA adapters in TRL scripts based on the core findings of the blog post. Afterwards, we'll revisit each finding in light of the TRL results.
|
| 19 |
+
|
| 20 |
+
### Supervised Fine-Tuning (SFT)
|
| 21 |
+
|
| 22 |
+
The blog post performs SFT on a range of models and datasets from the Hub, which we can reproduce in TRL.
|
| 23 |
+
|
| 24 |
+
| Model | Dataset |
|
| 25 |
+
| --- | --- |
|
| 26 |
+
| [Llama-3.2-1B-Instruct](https://huggingface.co/meta-llama/Llama-3.2-1B) | [allenai/tulu-3-sft-mixture](https://huggingface.co/datasets/allenai/tulu-3-sft-mixture) |
|
| 27 |
+
| [Llama-3.2-1B-Instruct](https://huggingface.co/meta-llama/Llama-3.2-1B) | [open-thoughts/OpenThoughts-114k](https://huggingface.co/datasets/open-thoughts/OpenThoughts-114k) |
|
| 28 |
+
| [Llama-3.1-8B-Instruct](https://huggingface.co/meta-llama/Llama-3.1-8B) | [allenai/tulu-3-sft-mixture](https://huggingface.co/datasets/allenai/tulu-3-sft-mixture) |
|
| 29 |
+
| [Llama-3.1-8B-Instruct](https://huggingface.co/meta-llama/Llama-3.1-8B) | [open-thoughts/OpenThoughts-114k](https://huggingface.co/datasets/open-thoughts/OpenThoughts-114k) |
|
| 30 |
+
|
| 31 |
+
<hfoptions id="sft">
|
| 32 |
+
<hfoption id="python">
|
| 33 |
+
|
| 34 |
+
We can integrate these findings with the TRL Python API like so:
|
| 35 |
+
|
| 36 |
+
```python
|
| 37 |
+
|
| 38 |
+
from datasets import load_dataset
|
| 39 |
+
from peft import LoraConfig
|
| 40 |
+
from trl import SFTTrainer, SFTConfig
|
| 41 |
+
|
| 42 |
+
dataset = load_dataset("open-thoughts/OpenThoughts-114k", split="train")
|
| 43 |
+
|
| 44 |
+
peft_config = LoraConfig(r=256, lora_alpha=16, target_modules="all-linear")
|
| 45 |
+
|
| 46 |
+
training_args = SFTConfig(
|
| 47 |
+
learning_rate=2e-4,
|
| 48 |
+
per_device_train_batch_size=1,
|
| 49 |
+
gradient_accumulation_steps=4,
|
| 50 |
+
num_train_epochs=1,
|
| 51 |
+
report_to=["trackio"],
|
| 52 |
+
)
|
| 53 |
+
|
| 54 |
+
trainer = SFTTrainer(
|
| 55 |
+
model="Qwen/Qwen2.5-3B-Instruct",
|
| 56 |
+
train_dataset=dataset,
|
| 57 |
+
peft_config=peft_config,
|
| 58 |
+
args=training_args,
|
| 59 |
+
)
|
| 60 |
+
|
| 61 |
+
trainer.train()
|
| 62 |
+
|
| 63 |
+
```
|
| 64 |
+
|
| 65 |
+
</hfoption>
|
| 66 |
+
<hfoption id="jobs">
|
| 67 |
+
|
| 68 |
+
```bash
|
| 69 |
+
|
| 70 |
+
hf jobs uv run \
|
| 71 |
+
--flavor a100-large \
|
| 72 |
+
--timeout 8h \
|
| 73 |
+
--secrets HF_TOKEN \
|
| 74 |
+
"https://raw.githubusercontent.com/huggingface/trl/main/trl/scripts/sft.py" \
|
| 75 |
+
--model_name_or_path Qwen/Qwen2.5-3B-Instruct \
|
| 76 |
+
--dataset_name open-thoughts/OpenThoughts-114k \
|
| 77 |
+
--learning_rate 2.0e-5 \
|
| 78 |
+
--num_train_epochs 1 \
|
| 79 |
+
--packing \
|
| 80 |
+
--per_device_train_batch_size 2 \
|
| 81 |
+
--gradient_accumulation_steps 16 \
|
| 82 |
+
--use_peft \
|
| 83 |
+
--lora_r 256 \
|
| 84 |
+
--lora_alpha 16 \
|
| 85 |
+
--lora_target_modules all-linear \
|
| 86 |
+
--output_dir Qwen2.5-3B-OpenThoughts-LoRA \
|
| 87 |
+
--report_to trackio \
|
| 88 |
+
--push_to_hub
|
| 89 |
+
|
| 90 |
+
```
|
| 91 |
+
|
| 92 |
+
To use Hugging Face Jobs, you will need to be logged in to the Hugging Face Hub (`hf auth login`) and have a [Pro](https://hf.co/pro), [Team](https://hf.co/enterprise), or [Enterprise](https://hf.co/enterprise) plan. Check out the [Jobs documentation](https://huggingface.co/docs/huggingface_hub/en/guides/jobs) for more details.
|
| 93 |
+
|
| 94 |
+
</hfoption>
|
| 95 |
+
<hfoption id="local">
|
| 96 |
+
|
| 97 |
+
```bash
|
| 98 |
+
|
| 99 |
+
uv run "https://raw.githubusercontent.com/huggingface/trl/main/trl/scripts/sft.py" \
|
| 100 |
+
--model_name_or_path Qwen/Qwen2.5-3B-Instruct \
|
| 101 |
+
--dataset_name open-thoughts/OpenThoughts-114k \
|
| 102 |
+
--learning_rate 2.0e-5 \
|
| 103 |
+
--num_train_epochs 1 \
|
| 104 |
+
--packing \
|
| 105 |
+
--per_device_train_batch_size 2 \
|
| 106 |
+
--gradient_accumulation_steps 16 \
|
| 107 |
+
--eval_strategy no \
|
| 108 |
+
--use_peft \
|
| 109 |
+
--lora_r 256 \
|
| 110 |
+
--lora_alpha 16 \
|
| 111 |
+
--lora_target_modules all-linear \
|
| 112 |
+
--output_dir Qwen2.5-3B-OpenThoughts-LoRA \
|
| 113 |
+
--report_to trackio \
|
| 114 |
+
--push_to_hub
|
| 115 |
+
|
| 116 |
+
```
|
| 117 |
+
|
| 118 |
+
To run the script locally, you will need to have `uv` installed. Check out the [uv documentation](https://docs.astral.sh/uv/) for more details.
|
| 119 |
+
|
| 120 |
+
</hfoption>
|
| 121 |
+
</hfoptions>
|
| 122 |
+
|
| 123 |
+
Once training starts, you can monitor the progress in [Trackio](https://huggingface.co/trackio), which will log the URL.
|
| 124 |
+
|
| 125 |
+
### Reinforcement Learning (GRPO)
|
| 126 |
+
|
| 127 |
+
The blog post performs GRPO on a range of models and datasets from the Hub, and once again we can reproduce the results in TRL.
|
| 128 |
+
|
| 129 |
+
| Model | Dataset |
|
| 130 |
+
| --- | --- |
|
| 131 |
+
| [Llama-3.1-8B-Base](https://huggingface.co/meta-llama/Llama-3.2-1B) | [GSM8k](https://huggingface.co/datasets/openai/gsm8k) |
|
| 132 |
+
| [Llama-3.1-8B-Base](https://huggingface.co/meta-llama/Llama-3.2-1B) | [DeepMath-103K](https://huggingface.co/datasets/zwhe99/DeepMath-103K) |
|
| 133 |
+
| [Qwen3-8b-base](https://huggingface.co/Qwen/Qwen3-8b-base) | [DeepMath-103K](https://huggingface.co/datasets/zwhe99/DeepMath-103K) |
|
| 134 |
+
|
| 135 |
+
For reinforcement learning, the blog uses a math reasoning task that we can reproduce as a Python function.
|
| 136 |
+
|
| 137 |
+
<hfoptions id="grpo">
|
| 138 |
+
<hfoption id="python">
|
| 139 |
+
|
| 140 |
+
We can implement these recommendations with the TRL Python API like so:
|
| 141 |
+
|
| 142 |
+
```python
|
| 143 |
+
|
| 144 |
+
from datasets import load_dataset
|
| 145 |
+
from peft import LoraConfig
|
| 146 |
+
from trl import GRPOConfig, GRPOTrainer
|
| 147 |
+
from trl.rewards import reasoning_accuracy_reward
|
| 148 |
+
|
| 149 |
+
dataset = load_dataset("HuggingFaceH4/OpenR1-Math-220k-default-verified", split="train")
|
| 150 |
+
|
| 151 |
+
peft_config = LoraConfig(
|
| 152 |
+
r=1,
|
| 153 |
+
lora_alpha=32,
|
| 154 |
+
target_modules="all-linear"
|
| 155 |
+
)
|
| 156 |
+
|
| 157 |
+
training_args = GRPOConfig(
|
| 158 |
+
learning_rate=5e-5,
|
| 159 |
+
per_device_train_batch_size=1,
|
| 160 |
+
gradient_accumulation_steps=4,
|
| 161 |
+
num_train_epochs=1,
|
| 162 |
+
num_generations=8,
|
| 163 |
+
generation_batch_size=8,
|
| 164 |
+
report_to=["trackio"],
|
| 165 |
+
)
|
| 166 |
+
|
| 167 |
+
trainer = GRPOTrainer(
|
| 168 |
+
model="Qwen/Qwen3-0.6B",
|
| 169 |
+
reward_funcs=reasoning_accuracy_reward,
|
| 170 |
+
args=training_args,
|
| 171 |
+
train_dataset=dataset,
|
| 172 |
+
peft_config=peft_config,
|
| 173 |
+
)
|
| 174 |
+
|
| 175 |
+
trainer.train()
|
| 176 |
+
|
| 177 |
+
```
|
| 178 |
+
|
| 179 |
+
> [!WARNING]
|
| 180 |
+
> This snippet skips the reward function which is defined above to keep the example concise.
|
| 181 |
+
|
| 182 |
+
</hfoption>
|
| 183 |
+
<hfoption id="jobs">
|
| 184 |
+
|
| 185 |
+
```bash
|
| 186 |
+
|
| 187 |
+
hf jobs uv run \
|
| 188 |
+
--flavor a100-large \
|
| 189 |
+
--timeout 4h \
|
| 190 |
+
--secrets HF_TOKEN \
|
| 191 |
+
--env PYTORCH_CUDA_ALLOC_CONF=expandable_segments:True \
|
| 192 |
+
"https://huggingface.co/datasets/burtenshaw/lora-without-regrets/resolve/main/grpo.py" \
|
| 193 |
+
--model_name_or_path Qwen/Qwen3-0.6B \
|
| 194 |
+
--dataset_name HuggingFaceH4/OpenR1-Math-220k-default-verified \
|
| 195 |
+
--output_dir grpo-full-qwen3-0.6b \
|
| 196 |
+
--learning_rate 1.0e-6 \
|
| 197 |
+
--lr_scheduler_type cosine \
|
| 198 |
+
--warmup_steps 0.0 \
|
| 199 |
+
--max_grad_norm 1.0 \
|
| 200 |
+
--beta 0.0 \
|
| 201 |
+
--max_completion_length 4096 \
|
| 202 |
+
--num_generations 16 \
|
| 203 |
+
--generation_batch_size 16 \
|
| 204 |
+
--gradient_accumulation_steps 8 \
|
| 205 |
+
--per_device_train_batch_size 1 \
|
| 206 |
+
--num_train_epochs 1 \
|
| 207 |
+
--lora_r 1 \
|
| 208 |
+
--lora_alpha 32 \
|
| 209 |
+
--lora_dropout 0.0 \
|
| 210 |
+
--lora_target_modules all-linear \
|
| 211 |
+
--vllm_mode colocate \
|
| 212 |
+
--save_strategy steps \
|
| 213 |
+
--save_steps 50 \
|
| 214 |
+
--save_total_limit 1 \
|
| 215 |
+
--logging_steps 1 \
|
| 216 |
+
--max_steps 200 \
|
| 217 |
+
--report_to trackio
|
| 218 |
+
```
|
| 219 |
+
|
| 220 |
+
To use Hugging Face Jobs, you will need to be logged in to the Hugging Face Hub (`hf auth login`) and have a [Pro](https://hf.co/pro), [Team](https://hf.co/enterprise), or [Enterprise](https://hf.co/enterprise) plan. Check out the [Jobs documentation](https://huggingface.co/docs/huggingface_hub/en/guides/jobs) for more details.
|
| 221 |
+
|
| 222 |
+
</hfoption>
|
| 223 |
+
<hfoption id="local">
|
| 224 |
+
|
| 225 |
+
```bash
|
| 226 |
+
uv run "https://huggingface.co/datasets/burtenshaw/lora-without-regrets/resolve/main/grpo.py" \
|
| 227 |
+
--model_name_or_path Qwen/Qwen3-0.6B \
|
| 228 |
+
--dataset_name HuggingFaceH4/OpenR1-Math-220k-default-verified \
|
| 229 |
+
--output_dir grpo-full-qwen3-0.6b \
|
| 230 |
+
--learning_rate 1.0e-6 \
|
| 231 |
+
--lr_scheduler_type cosine \
|
| 232 |
+
--warmup_steps 0.0 \
|
| 233 |
+
--max_grad_norm 1.0 \
|
| 234 |
+
--beta 0.0 \
|
| 235 |
+
--max_completion_length 4096 \
|
| 236 |
+
--num_generations 16 \
|
| 237 |
+
--generation_batch_size 16 \
|
| 238 |
+
--gradient_accumulation_steps 8 \
|
| 239 |
+
--per_device_train_batch_size 1 \
|
| 240 |
+
--num_train_epochs 1 \
|
| 241 |
+
--lora_r 1 \
|
| 242 |
+
--lora_alpha 32 \
|
| 243 |
+
--lora_dropout 0.0 \
|
| 244 |
+
--lora_target_modules all-linear \
|
| 245 |
+
--vllm_mode colocate \
|
| 246 |
+
--save_strategy steps \
|
| 247 |
+
--save_steps 50 \
|
| 248 |
+
--save_total_limit 1 \
|
| 249 |
+
--logging_steps 1 \
|
| 250 |
+
--max_steps 200 \
|
| 251 |
+
--report_to trackio
|
| 252 |
+
```
|
| 253 |
+
|
| 254 |
+
To run the script locally, you will need to have `uv` installed. Check out the [uv documentation](https://docs.astral.sh/uv/) for more details.
|
| 255 |
+
|
| 256 |
+
</hfoption>
|
| 257 |
+
</hfoptions>
|
| 258 |
+
|
| 259 |
+
The reinforcement learning script with GRPO is implemented as a custom script in TRL, which uses the reward function shown above. You can review it at [`grpo.py`](https://huggingface.co/datasets/burtenshaw/lora-without-regrets/blob/main/grpo.py) - Reinforcement learning with LoRA best practices
|
| 260 |
+
|
| 261 |
+
## Key findings in optimizing LoRA
|
| 262 |
+
|
| 263 |
+
The authors recommend applying LoRA to all weight matrices rather than limiting it to attention layers, as increasing the rank does not compensate for this restriction. In TRL, this can be configured using `--lora_target_modules all-linear` to apply LoRA to all weight matrices.
|
| 264 |
+
|
| 265 |
+
We were able to reproduce the results of the blog post using TRL and the SmolLM3 model. We trained the model for 500 steps on the [Math 220k dataset](https://huggingface.co/datasets/HuggingFaceH4/OpenR1-Math-220k-default-verified) with the reward function and configuration above. As you can see in the figure below, the LoRA model's average train reward curve matches the full fine-tuning curve.
|
| 266 |
+
|
| 267 |
+

|
| 268 |
+
|
| 269 |
+
And most importantly, the LoRA model uses significantly less memory than the full fine-tuning model, as we can see in the figure below.
|
| 270 |
+
|
| 271 |
+

|
| 272 |
+
|
| 273 |
+
Here are the parameters we used to train the above models
|
| 274 |
+
|
| 275 |
+
| Parameter | LoRA | Full FT |
|
| 276 |
+
| --- | --- | --- |
|
| 277 |
+
| `--model_name_or_path` | HuggingFaceTB/SmolLM3-3B | HuggingFaceTB/SmolLM3-3B |
|
| 278 |
+
| `--dataset_name` | HuggingFaceH4/OpenR1-Math-220k-default-verified | HuggingFaceH4/OpenR1-Math-220k-default-verified |
|
| 279 |
+
| `--learning_rate` | 1.0e-5 | 1.0e-6 |
|
| 280 |
+
| `--max_completion_length` | 4096 | 4096 |
|
| 281 |
+
| `--lora_r` | 1 | - |
|
| 282 |
+
| `--lora_alpha` | 32 | - |
|
| 283 |
+
| `--lora_dropout` | 0.0 | - |
|
| 284 |
+
| `--lora_target_modules` | all-linear | - |
|
| 285 |
+
|
| 286 |
+
Let's break down the key findings of the blog post and how we were able to reproduce them.
|
| 287 |
+
|
| 288 |
+
### 1. *LoRA performs better when applied to all weight matrices*
|
| 289 |
+
|
| 290 |
+
The authors recommend applying LoRA to all weight matrices rather than limiting it to attention layers, as increasing the rank does not compensate for this restriction.
|
| 291 |
+
|
| 292 |
+

|
| 293 |
+
|
| 294 |
+
Attention-only LoRA underperforms even when using a higher rank to match parameter count. In TRL, this can be configured using `--lora_target_modules all-linear` to apply LoRA to all weight matrices. In Python, we can do this like so:
|
| 295 |
+
|
| 296 |
+
```python
|
| 297 |
+
from peft import LoraConfig
|
| 298 |
+
|
| 299 |
+
peft_config = LoraConfig(target_modules="all-linear")
|
| 300 |
+
```
|
| 301 |
+
|
| 302 |
+
### 2. *The adapter needs sufficient capacity to learn from the dataset*
|
| 303 |
+
|
| 304 |
+
The blog post recommends using a sufficient LoRA rank to learn from the dataset. The rank determines the number of trainable parameters in the LoRA adapter. Therefore, "For datasets that exceed LoRA capacity, LoRA underperforms FullFT".
|
| 305 |
+
|
| 306 |
+

|
| 307 |
+
|
| 308 |
+
In the TRL script, we could use `--lora_r` to set the rank and adapt it based on the task and dataset we're training on. The blog post recommends the following ranks based on the task and dataset size:
|
| 309 |
+
|
| 310 |
+
Reinforcement learning tasks typically require lower capacity, so smaller LoRA ranks can be used. This is because policy gradient algorithms extract roughly ~1 bit of information per episode, demanding minimal parameter capacity.
|
| 311 |
+
|
| 312 |
+
The blog post defines the ideal dataset size for LoRA to match full fine-tuning as "Post-training scale". Which we can use to determine the recommended rank for SFT and RL LoRAs as:
|
| 313 |
+
|
| 314 |
+
| Task Type | Dataset Size | Recommended Rank |
|
| 315 |
+
| --- | --- | --- |
|
| 316 |
+
| **SFT** | Post-training scale | 256 |
|
| 317 |
+
| **RL** | Any size | 1-32 |
|
| 318 |
+
|
| 319 |
+
### 3. *"FullFT and high-rank LoRAs have similar learning curves"*
|
| 320 |
+
|
| 321 |
+
Counterintuitively, the blog post recommends using a higher learning rate than for full fine-tuning. In the table above, we used 1.0e-5 for LoRA and 1.0e-6 for full fine-tuning. In the TRL script, we could use `--learning_rate` to set the learning rate. The \\( \frac{1}{r} \\) scaling in LoRA makes the optimal learning rate approximately rank-independent.
|
| 322 |
+
|
| 323 |
+

|
| 324 |
+
|
| 325 |
+
### 4. *"In some scenarios, LoRA is less tolerant of large batch sizes than full fine-tuning."*
|
| 326 |
+
|
| 327 |
+
The blog post recommends using an effective batch size < 32 because the authors found LoRA to be less tolerant of large batch sizes. This could not be mitigated by increasing the LoRA rank. In the TRL script, we could use `--per_device_train_batch_size` and `--gradient_accumulation_steps` to set the batch size.
|
| 328 |
+
|
| 329 |
+

|
| 330 |
+
|
| 331 |
+
## Takeaways
|
| 332 |
+
|
| 333 |
+
Using TRL, you can efficiently implement LoRA adapters to match full fine-tuning performance, applying the core insights (targeting all weight matrices, choosing the right rank, and managing batch size and learning rate) without the heavy compute cost of FullFT.
|
| 334 |
+
|
| 335 |
+
## Citation
|
| 336 |
+
|
| 337 |
+
```bibtex
|
| 338 |
+
@article{schulman2025lora,
|
| 339 |
+
title = {{LoRA Without Regret}},
|
| 340 |
+
author = {John Schulman and Thinking Machines Lab},
|
| 341 |
+
year = 2025,
|
| 342 |
+
journal = {Thinking Machines Lab: Connectionism},
|
| 343 |
+
doi = {10.64434/tml.20250929},
|
| 344 |
+
note = {https://thinkingmachines.ai/blog/lora/}
|
| 345 |
+
}
|
| 346 |
+
```
|
tasks/tasksmith-1c108f674e97/tests/source/docs/source/merge_model_callback.md
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# MergeModelCallback
|
| 2 |
+
|
| 3 |
+
[[autodoc]] experimental.merge_model_callback.MergeModelCallback
|
tasks/tasksmith-1c108f674e97/tests/source/docs/source/minillm_trainer.md
ADDED
|
@@ -0,0 +1,67 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# MiniLLM Trainer
|
| 2 |
+
|
| 3 |
+
[](https://huggingface.co/models?other=minillm,trl)
|
| 4 |
+
|
| 5 |
+
## Overview
|
| 6 |
+
|
| 7 |
+
TRL supports the MiniLLM Trainer for distilling large language models into smaller ones using reverse KLD for better precision, quality, and performance, as described in the paper [Knowledge Distillation of Large Language Models](https://huggingface.co/papers/2306.08543) by [Yuxian Gu](https://huggingface.co/t1101675), [Li Dong](https://huggingface.co/unilm), [Furu Wei](https://huggingface.co/thegenerality), and Minlie Huang.
|
| 8 |
+
The abstract from the paper is the following:
|
| 9 |
+
|
| 10 |
+
> Knowledge Distillation (KD) is a promising technique for reducing the high computational demand of large language models (LLMs). However, previous KD methods are primarily applied to white-box classification models or training small models to imitate black-box model APIs like ChatGPT. How to effectively distill the knowledge from white-box generative LLMs is still under-explored, which becomes more and more important with the prosperity of LLMs. In this work, we propose MiniLLM that distills smaller language models from generative larger language models. We first replace the forward Kullback-Leibler divergence (KLD) objective in the standard KD approaches with reverse KLD, which is more suitable for KD on generative language models, to prevent the student model from overestimating the low-probability regions of the teacher distribution. Then, we derive an effective optimization approach to learn this objective. Extensive experiments in the instruction-following setting show that the MiniLLM models generate more precise responses with the higher overall quality, lower exposure bias, better calibration, and higher long-text generation performance. Our method is also scalable for different model families with 120M to 13B parameters. We will release our code and model checkpoints at https://aka.ms/MiniLLM.
|
| 11 |
+
|
| 12 |
+
This post-training method was contributed by [Yuxian Gu](https://huggingface.co/t1101675).
|
| 13 |
+
|
| 14 |
+
It is a generalized version of [Think Machine Lab's On-Policy Distillation](https://thinkingmachines.ai/blog/on-policy-distillation/), with the option to add distribution-level single-step distillation signals (like GKD when `beta=1`) and long-context reverse KLD signals.
|
| 15 |
+
|
| 16 |
+
$$
|
| 17 |
+
\begin{align}
|
| 18 |
+
L_{\text{MiniLLM}}&=\alpha_1\mathbb{E}_{x\sim \pi_{\theta}}\sum_{t'=t}^{|x|}\frac{\gamma^{t'-t}}{\sum_{t'}\gamma^{t'-t}}\left[\log \frac{\pi_{\theta}(x_{t'+1}|x_{1..t'})}{\pi_{\text{teacher}}(x_{t'+1}|x_{1..t'})}\right] \\
|
| 19 |
+
&+ \alpha_2\mathbb{E}_{x\sim \pi_{\theta}} \text{KL}\left[\pi_\theta(\cdot|x_{1..t})||\pi_{\text{teacher}}(\cdot | x_{1..t})\right].
|
| 20 |
+
\end{align}
|
| 21 |
+
$$
|
| 22 |
+
|
| 23 |
+
When \\( \alpha_1=1 \\), \\( \alpha_2=0 \\), \\( \gamma=0 \\), which corresponds to
|
| 24 |
+
|
| 25 |
+
```python
|
| 26 |
+
from trl.experimental.minillm import MiniLLMConfig
|
| 27 |
+
|
| 28 |
+
training_args = MiniLLMConfig(
|
| 29 |
+
rkl_advantage=True,
|
| 30 |
+
single_step_decomposition=False,
|
| 31 |
+
gamma=False
|
| 32 |
+
)
|
| 33 |
+
```
|
| 34 |
+
|
| 35 |
+
\\( L_{\text{MiniLLM}} \\) becomes the on-policy KD implemented in [Tinker](https://github.com/thinking-machines-lab/tinker-cookbook/blob/5d08be6d130596b7bedd02197861c41fa81ea436/tinker_cookbook/distillation/train_on_policy.py#L88):
|
| 36 |
+
|
| 37 |
+
$$
|
| 38 |
+
L_{\text{tinker}}=\mathbb{E}_{x\sim \pi_{\theta}}\left[\log \frac{\pi_{\theta}(x_{t'+1}|x_{1..t'})}{\pi_{\text{teacher}}(x_{t'+1}|x_{1..t'})}\right].
|
| 39 |
+
$$
|
| 40 |
+
|
| 41 |
+
When \\( \alpha_1=0 \\), \\( \alpha_2=1 \\), which corresponds to
|
| 42 |
+
|
| 43 |
+
```python
|
| 44 |
+
from trl.experimental.minillm import MiniLLMConfig
|
| 45 |
+
|
| 46 |
+
training_args = MiniLLMConfig(
|
| 47 |
+
rkl_advantage=False,
|
| 48 |
+
single_step_decomposition=True
|
| 49 |
+
)
|
| 50 |
+
```
|
| 51 |
+
|
| 52 |
+
\\( L_{\text{MiniLLM}} \\) becomes the reverse KLD version of the GKD loss as in [GKD Trainer](./gkd.md):
|
| 53 |
+
|
| 54 |
+
$$
|
| 55 |
+
L_{\text{GKD-RKL}}=\mathbb{E}_{x\sim \pi_{\theta}} \text{KL}\left[\pi_\theta(\cdot|x_{1..t})||\pi_{\text{teacher}}(\cdot | x_{1..t})\right].
|
| 56 |
+
$$
|
| 57 |
+
|
| 58 |
+
## MiniLLMTrainer
|
| 59 |
+
|
| 60 |
+
[[autodoc]] experimental.minillm.MiniLLMTrainer
|
| 61 |
+
- train
|
| 62 |
+
- save_model
|
| 63 |
+
- push_to_hub
|
| 64 |
+
|
| 65 |
+
## MiniLLMConfig
|
| 66 |
+
|
| 67 |
+
[[autodoc]] experimental.minillm.MiniLLMConfig
|
tasks/tasksmith-1c108f674e97/tests/source/docs/source/nash_md_trainer.md
ADDED
|
@@ -0,0 +1,140 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Nash-MD Trainer
|
| 2 |
+
|
| 3 |
+
[](https://huggingface.co/models?other=nash-md,trl)
|
| 4 |
+
|
| 5 |
+
## Overview
|
| 6 |
+
|
| 7 |
+
Nash-MD was proposed in the paper [Nash Learning from Human Feedback](https://huggingface.co/papers/2312.00886) by Rémi Munos, [Michal Valko](https://huggingface.co/misovalko), Daniele Calandriello, Mohammad Gheshlaghi Azar, Mark Rowland, Daniel Guo, Yunhao Tang, Matthieu Geist, Thomas Mésnard, and Andrea Michi.
|
| 8 |
+
|
| 9 |
+
The abstract from the paper is the following:
|
| 10 |
+
|
| 11 |
+
> Reinforcement learning from human feedback (RLHF) has emerged as the main paradigm for aligning large language models (LLMs) with human preferences. Typically, RLHF involves the initial step of learning a reward model from human feedback, often expressed as preferences between pairs of text generations produced by a pre-trained LLM. Subsequently, the LLM's policy is fine-tuned by optimizing it to maximize the reward model through a reinforcement learning algorithm. However, an inherent limitation of current reward models is their inability to fully represent the richness of human preferences and their dependency on the sampling distribution. In this study, we introduce an alternative pipeline for the fine-tuning of LLMs using pairwise human feedback. Our approach entails the initial learning of a preference model, which is conditioned on two inputs given a prompt, followed by the pursuit of a policy that consistently generates responses preferred over those generated by any competing policy, thus defining the Nash equilibrium of this preference model. We term this approach Nash learning from human feedback (NLHF). In the context of a tabular policy representation, we present a novel algorithmic solution, Nash-MD, founded on the principles of mirror descent. This algorithm produces a sequence of policies, with the last iteration converging to the regularized Nash equilibrium. Additionally, we explore parametric representations of policies and introduce gradient descent algorithms for deep-learning architectures. To demonstrate the effectiveness of our approach, we present experimental results involving the fine-tuning of a LLM for a text summarization task. We believe NLHF offers a compelling avenue for preference learning and policy optimization with the potential of advancing the field of aligning LLMs with human preferences.
|
| 12 |
+
|
| 13 |
+
This post-training method was contributed by [Kashif Rasul](https://huggingface.co/kashif) and [Daniil Tiapkin](https://huggingface.co/dtiapkin), [Pierre Ménard](https://huggingface.co/menardprr), Daniele Calandriello and [Quentin Gallouédec](https://huggingface.co/qgallouedec).
|
| 14 |
+
|
| 15 |
+
## Quick start
|
| 16 |
+
|
| 17 |
+
This example demonstrates how to train a model using the Nash-MD method. We use the [Qwen 0.5B model](https://huggingface.co/Qwen/Qwen2-0.5B-Instruct) as the base model and the [trl-lib/Qwen2-0.5B-Reward](https://huggingface.co/trl-lib/Qwen2-0.5B-Reward) reward model. We use the prompts from the [UltraFeedback dataset](https://huggingface.co/datasets/openbmb/UltraFeedback). You can view the prompts in the dataset here:
|
| 18 |
+
|
| 19 |
+
<iframe
|
| 20 |
+
src="https://huggingface.co/datasets/trl-lib/ultrafeedback-prompt/embed/viewer/default/train?row=0"
|
| 21 |
+
frameborder="0"
|
| 22 |
+
width="100%"
|
| 23 |
+
height="560px"
|
| 24 |
+
></iframe>
|
| 25 |
+
|
| 26 |
+
Below is the script to train the model:
|
| 27 |
+
|
| 28 |
+
```python
|
| 29 |
+
# train_nash_md.py
|
| 30 |
+
from datasets import load_dataset
|
| 31 |
+
from trl.experimental.nash_md import NashMDConfig, NashMDTrainer
|
| 32 |
+
from transformers import AutoModelForCausalLM, AutoModelForSequenceClassification, AutoTokenizer
|
| 33 |
+
|
| 34 |
+
model = AutoModelForCausalLM.from_pretrained("Qwen/Qwen2-0.5B-Instruct")
|
| 35 |
+
tokenizer = AutoTokenizer.from_pretrained("Qwen/Qwen2-0.5B-Instruct")
|
| 36 |
+
reward_model = AutoModelForSequenceClassification.from_pretrained("trl-lib/Qwen2-0.5B-Reward", num_labels=1)
|
| 37 |
+
train_dataset = load_dataset("trl-lib/ultrafeedback-prompt", split="train")
|
| 38 |
+
|
| 39 |
+
training_args = NashMDConfig(output_dir="Qwen2-0.5B-NashMD")
|
| 40 |
+
trainer = NashMDTrainer(
|
| 41 |
+
model=model, reward_funcs=reward_model, args=training_args, processing_class=tokenizer, train_dataset=train_dataset
|
| 42 |
+
)
|
| 43 |
+
trainer.train()
|
| 44 |
+
```
|
| 45 |
+
|
| 46 |
+
Execute the script using the following command:
|
| 47 |
+
|
| 48 |
+
```bash
|
| 49 |
+
accelerate launch train_nash_md.py
|
| 50 |
+
```
|
| 51 |
+
|
| 52 |
+
Distributed across 8 GPUs, the training takes approximately 3 hours.
|
| 53 |
+
|
| 54 |
+
To see how the [trained model](https://huggingface.co/trl-lib/Qwen2-0.5B-NashMD) performs, you can use the [Transformers Chat CLI](https://huggingface.co/docs/transformers/quicktour#chat-with-text-generation-models).
|
| 55 |
+
|
| 56 |
+
<pre><code>$ transformers chat trl-lib/Qwen2-0.5B-NashMD
|
| 57 |
+
<strong><span style="color: red;"><quentin_gallouedec>:</span></strong>
|
| 58 |
+
What is the best programming language?
|
| 59 |
+
|
| 60 |
+
<strong><span style="color: blue;"><trl-lib/Qwen2-0.5B-NashMD>:</span></strong>
|
| 61 |
+
The best programming language depends on personal preference, the complexity of the project, and the specific requirements of the task. Some programming languages that are often recommended include Python, Java, and JavaScript, and there are many other languages to choose from depending on individual needs.
|
| 62 |
+
</code></pre>
|
| 63 |
+
|
| 64 |
+
## Expected dataset type
|
| 65 |
+
|
| 66 |
+
Nash-MD requires a [prompt-only dataset](dataset_formats#prompt-only). The [`experimental.nash_md.NashMDTrainer`] supports both [conversational](dataset_formats#conversational) and [standard](dataset_formats#standard) dataset formats. When provided with a conversational dataset, the trainer will automatically apply the chat template to the dataset.
|
| 67 |
+
|
| 68 |
+
## Usage tips
|
| 69 |
+
|
| 70 |
+
### Encourage EOS token generation
|
| 71 |
+
|
| 72 |
+
We may want the model to generate completions within a given length. During training, the model will generate completions up to the maximum length specified in the `max_new_tokens` argument of [`experimental.nash_md.NashMDConfig`]. If you want to penalize the model for not generating an EOS token before reaching the maximum length, you can use the `missing_eos_penalty` argument of [`experimental.nash_md.NashMDConfig`]:
|
| 73 |
+
|
| 74 |
+
```python
|
| 75 |
+
training_args = NashMDConfig(..., max_new_tokens=128, missing_eos_penalty=1.0)
|
| 76 |
+
```
|
| 77 |
+
|
| 78 |
+
> [!WARNING]
|
| 79 |
+
> Make sure that the SFT model and reward model use the _same_ chat template and the same tokenizer. Otherwise, you may find the model completions are scored incorrectly during training.
|
| 80 |
+
|
| 81 |
+
### Logging Completions
|
| 82 |
+
|
| 83 |
+
To better understand your model's behavior during training, you can log sample completions periodically using the [`LogCompletionsCallback`].
|
| 84 |
+
|
| 85 |
+
```python
|
| 86 |
+
trainer = NashMDTrainer(..., eval_dataset=eval_dataset)
|
| 87 |
+
completions_callback = LogCompletionsCallback(trainer, num_prompts=8)
|
| 88 |
+
trainer.add_callback(completions_callback)
|
| 89 |
+
```
|
| 90 |
+
|
| 91 |
+
This callback logs the model's generated completions directly to Weights & Biases.
|
| 92 |
+
|
| 93 |
+

|
| 94 |
+
|
| 95 |
+
## Example script
|
| 96 |
+
|
| 97 |
+
We provide an example script to train a model using the Nash-MD method. The script is available in [`examples/scripts/nash_md.py`](https://github.com/huggingface/trl/blob/main/examples/scripts/nash_md.py)
|
| 98 |
+
|
| 99 |
+
To test the Nash-MD script with the [Qwen2.5 0.5B model](https://huggingface.co/trl-lib/Qwen/Qwen2.5-0.5B-Instruct) on the [UltraFeedback dataset](https://huggingface.co/datasets/openbmb/UltraFeedback), run the following command:
|
| 100 |
+
|
| 101 |
+
```bash
|
| 102 |
+
python examples/scripts/nash_md.py \
|
| 103 |
+
--model_name_or_path Qwen/Qwen2.5-0.5B-Instruct \
|
| 104 |
+
--reward_model_path trl-lib/Qwen2-0.5B-Reward \
|
| 105 |
+
--dataset_name trl-lib/ultrafeedback-prompt \
|
| 106 |
+
--learning_rate 5.0e-7 \
|
| 107 |
+
--output_dir Qwen2.5-0.5B-NashMD \
|
| 108 |
+
--warmup_steps 0.1 \
|
| 109 |
+
--push_to_hub
|
| 110 |
+
```
|
| 111 |
+
|
| 112 |
+
## Logged metrics
|
| 113 |
+
|
| 114 |
+
While training and evaluating, we record the following reward metrics:
|
| 115 |
+
|
| 116 |
+
* `loss/kl`: The mean KL divergence between the model and reference data.
|
| 117 |
+
* `objective/entropy`: The mean entropy of the model and reference data.
|
| 118 |
+
* `loss/score`: The mean reinforce score loss.
|
| 119 |
+
* `rewards/chosen`: The mean scores (according to the reward model) of the model completions.
|
| 120 |
+
* `rewards/rejected`: The mean scores (according to the reward model) of the mixture completions.
|
| 121 |
+
* `rewards/probabilities`: The mean probability (according to the reward model) of the model completions chosen vs the mixture completion.
|
| 122 |
+
* `rewards/accuracies`: The accuracies of the Nash-MD's implicit reward model.
|
| 123 |
+
* `rewards/margins`: The mean reward margin (according to reward model) between the chosen and mixture completions.
|
| 124 |
+
* `logps/chosen`: The mean log probabilities of the chosen completions.
|
| 125 |
+
* `logps/rejected`: The mean log probabilities of the reference completions.
|
| 126 |
+
* `val/model_contain_eos_token`: The amount of times the model's output contains the eos token.
|
| 127 |
+
* `val/ref_contain_eos_token`: The amount of times the mixture's output contains the eos token.
|
| 128 |
+
* `beta`: The parameter that controls the weight of the loss term representing the deviation from the reference model. Typically fixed, but can be made dynamic by passing a list to [`experimental.nash_md.NashMDConfig`].
|
| 129 |
+
* `mixture_coef`: Logit mixture coefficient for the model and reference model. Typically fixed, but can be made dynamic by passing a list to [`experimental.nash_md.NashMDConfig`].
|
| 130 |
+
|
| 131 |
+
## NashMDTrainer
|
| 132 |
+
|
| 133 |
+
[[autodoc]] experimental.nash_md.NashMDTrainer
|
| 134 |
+
- train
|
| 135 |
+
- save_model
|
| 136 |
+
- push_to_hub
|
| 137 |
+
|
| 138 |
+
## NashMDConfig
|
| 139 |
+
|
| 140 |
+
[[autodoc]] experimental.nash_md.NashMDConfig
|
tasks/tasksmith-1c108f674e97/tests/source/docs/source/nemo_gym.md
ADDED
|
@@ -0,0 +1,293 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# NeMo Gym Integration
|
| 2 |
+
|
| 3 |
+
NVIDIA NeMo Gym is a library for building RL environments for large language models. This integration enables training models in NeMo Gym environments using TRL's GRPOTrainer with vLLM server mode.
|
| 4 |
+
|
| 5 |
+
The integration supports multi-step and multi-turn rollouts, multi-environment training, and any NeMo Gym environment (thoroughly tested: workplace assistant, reasoning gym, MCQA, and math with judge).
|
| 6 |
+
|
| 7 |
+
## Why NeMo Gym
|
| 8 |
+
|
| 9 |
+
- **Production-Ready Scale**: Tested for frontier model training with diverse environments running in parallel across math, coding, tool use, reasoning, and more.
|
| 10 |
+
- **Multi-Verifier Training**: Supports algorithmic verification, LLM-as-a-judge, and custom verification logic in a single training run.
|
| 11 |
+
- **Decoupled Architecture**: Build agents and environments independently from the training loop—no RL framework expertise required.
|
| 12 |
+
- **OpenAI-Compatible API**: All environments use the standardized OpenAI Responses API for seamless integration with vLLM, OpenAI models, and other endpoints.
|
| 13 |
+
|
| 14 |
+
## Available Environments
|
| 15 |
+
|
| 16 |
+
NeMo Gym provides training-ready environments across multiple domains, including but not limited to:
|
| 17 |
+
|
| 18 |
+
| Environment | Domain | Description |
|
| 19 |
+
|-------------|--------|-------------|
|
| 20 |
+
| Workplace Assistant | Agent | Multi-step tool calling in common office scenarios (calendar, email, and more) |
|
| 21 |
+
| Math with Judge | Math | Math problems with algorithmic or judge-based verification |
|
| 22 |
+
| Code Gen | Coding | Competitive programming problems with code execution |
|
| 23 |
+
| MCQA | Knowledge | Multiple-choice question answering |
|
| 24 |
+
| Instruction Following | Instruction Following | IFEval/IFBench style tasks |
|
| 25 |
+
| Reasoning Gym | Multiple | Single-step procedurally generated verifiable tasks across domains |
|
| 26 |
+
|
| 27 |
+
For a complete list of available training environments, refer to the [NeMo Gym repository](https://github.com/NVIDIA-NeMo/Gym#-available-resource-servers).
|
| 28 |
+
|
| 29 |
+
## Before You Start
|
| 30 |
+
|
| 31 |
+
Complete these one-time setup steps before running training.
|
| 32 |
+
|
| 33 |
+
### Install TRL and NeMo Gym
|
| 34 |
+
|
| 35 |
+
1. **Install TRL with vLLM extras**
|
| 36 |
+
|
| 37 |
+
```bash
|
| 38 |
+
cd trl/
|
| 39 |
+
uv venv
|
| 40 |
+
source .venv/bin/activate
|
| 41 |
+
uv sync --extra vllm
|
| 42 |
+
```
|
| 43 |
+
|
| 44 |
+
1. **Install NeMo Gym**
|
| 45 |
+
|
| 46 |
+
```bash
|
| 47 |
+
# deactivate trl venv
|
| 48 |
+
deactivate
|
| 49 |
+
git clone https://github.com/NVIDIA-NeMo/Gym.git
|
| 50 |
+
cd Gym
|
| 51 |
+
uv venv --python 3.12
|
| 52 |
+
source .venv/bin/activate
|
| 53 |
+
uv sync
|
| 54 |
+
```
|
| 55 |
+
|
| 56 |
+
### Prepare a Dataset
|
| 57 |
+
|
| 58 |
+
Many NeMo Gym datasets used to train Nemotron models are available on Hugging Face. Use `ng_prepare_data` to download and prepare datasets. This command:
|
| 59 |
+
|
| 60 |
+
- Downloads the dataset from Hugging Face
|
| 61 |
+
- Validates the data format
|
| 62 |
+
- Adds an `agent_ref` field to each example that tells NeMo Gym which agent server should handle that example
|
| 63 |
+
|
| 64 |
+
> **Note**: `train_multi_environment.py` adds the `agent_ref` field when loading datasets, so this step is optional if datasets are created another way.
|
| 65 |
+
|
| 66 |
+
1. **Set Hugging Face Token**
|
| 67 |
+
|
| 68 |
+
Create `env.yaml` in `Gym/` with your HF token:
|
| 69 |
+
|
| 70 |
+
```yaml
|
| 71 |
+
hf_token: <your_hf_token>
|
| 72 |
+
```
|
| 73 |
+
|
| 74 |
+
1. **Prepare Dataset**
|
| 75 |
+
|
| 76 |
+
```bash
|
| 77 |
+
# Enter Gym and activate the venv
|
| 78 |
+
cd Gym
|
| 79 |
+
source .venv/bin/activate
|
| 80 |
+
|
| 81 |
+
# Set config paths
|
| 82 |
+
config_paths="responses_api_models/vllm_model/configs/vllm_model.yaml,\
|
| 83 |
+
resources_servers/workplace_assistant/configs/workplace_assistant.yaml"
|
| 84 |
+
|
| 85 |
+
# Download data and prep for training
|
| 86 |
+
ng_prepare_data "+config_paths=[${config_paths}]" \
|
| 87 |
+
+output_dirpath=data/workplace_assistant \
|
| 88 |
+
+mode=train_preparation \
|
| 89 |
+
+should_download=true \
|
| 90 |
+
+data_source=huggingface
|
| 91 |
+
```
|
| 92 |
+
|
| 93 |
+
This creates `train.jsonl` and `validation.jsonl` files in `data/workplace_assistant/`.
|
| 94 |
+
|
| 95 |
+
To create a new environment, refer to the [environment creation guide](https://docs.nvidia.com/nemo/gym/latest/contribute/environments/new-environment.html). We suggest running an existing one first!
|
| 96 |
+
|
| 97 |
+
#### Dataset Format
|
| 98 |
+
|
| 99 |
+
NeMo Gym datasets are stored as JSONL. Each line contains a task with input messages, tool definitions, metadata such as ground truth for verification, and an agent server reference. The following example shows the workplace dataset structure. Metadata fields can differ between datasets, as long as the corresponding resources server uses the fields appropriately.
|
| 100 |
+
|
| 101 |
+
```json
|
| 102 |
+
{
|
| 103 |
+
"responses_create_params": {
|
| 104 |
+
"input": [
|
| 105 |
+
{"role": "system", "content": "..."},
|
| 106 |
+
{"role": "user", "content": "Move any of jinsoo's tasks that are in review to completed"}
|
| 107 |
+
],
|
| 108 |
+
"tools": [...],
|
| 109 |
+
"parallel_tool_calls": false,
|
| 110 |
+
"temperature": 1
|
| 111 |
+
},
|
| 112 |
+
"ground_truth": [
|
| 113 |
+
{"name": "project_management_update_task", "arguments": "{...}"},
|
| 114 |
+
...
|
| 115 |
+
],
|
| 116 |
+
"category": "workbench_project_management",
|
| 117 |
+
"environment_name": "workbench",
|
| 118 |
+
"agent_ref": {
|
| 119 |
+
"type": "responses_api_agents",
|
| 120 |
+
"name": "workplace_assistant_simple_agent"
|
| 121 |
+
}
|
| 122 |
+
}
|
| 123 |
+
```
|
| 124 |
+
|
| 125 |
+
## Interactive Training
|
| 126 |
+
|
| 127 |
+
For development and testing on a single node.
|
| 128 |
+
|
| 129 |
+
### Set Up
|
| 130 |
+
|
| 131 |
+
1. **Update Environment Config**
|
| 132 |
+
|
| 133 |
+
Update `env.yaml` in `Gym/` to include model information:
|
| 134 |
+
|
| 135 |
+
```yaml
|
| 136 |
+
policy_base_url: http://127.0.0.1:8000/v1
|
| 137 |
+
policy_api_key: EMPTY
|
| 138 |
+
policy_model_name: Qwen/Qwen2.5-1.5B-Instruct
|
| 139 |
+
hf_token: ...
|
| 140 |
+
```
|
| 141 |
+
|
| 142 |
+
2. **Update Training Config**
|
| 143 |
+
|
| 144 |
+
Update `examples/scripts/nemo_gym/config.yaml` to point to the dataset generated above, and any other optional modifications.
|
| 145 |
+
|
| 146 |
+
### Run Training
|
| 147 |
+
|
| 148 |
+
The following steps run in 3 terminals. It can also be ran with processes in the background, or using tmux.
|
| 149 |
+
|
| 150 |
+
1. **Start NeMo Gym Servers** (Terminal 1)
|
| 151 |
+
|
| 152 |
+
```bash
|
| 153 |
+
cd Gym/
|
| 154 |
+
source .venv/bin/activate
|
| 155 |
+
|
| 156 |
+
config_paths="resources_servers/workplace_assistant/configs/workplace_assistant.yaml,\
|
| 157 |
+
responses_api_models/vllm_model/configs/vllm_model_for_training.yaml"
|
| 158 |
+
|
| 159 |
+
ng_run "+config_paths=[${config_paths}]"
|
| 160 |
+
```
|
| 161 |
+
|
| 162 |
+
This starts:
|
| 163 |
+
- **Agent server**: Orchestrates rollouts using resource servers and model servers
|
| 164 |
+
- **Resources server**: Supports environment logic such as state-management, tool implementations, and task verification
|
| 165 |
+
- **Model server**: Adapts vLLM server requests to support NeMo Gym agents and on-policy RL training while ensuring OpenAI API compatibility
|
| 166 |
+
- **Head server**: Manages servers used in training enabling their discovery
|
| 167 |
+
|
| 168 |
+
1. **Start TRL vLLM Server on GPU 0** (Terminal 2)
|
| 169 |
+
|
| 170 |
+
```bash
|
| 171 |
+
cd trl/
|
| 172 |
+
source .venv/bin/activate
|
| 173 |
+
CUDA_VISIBLE_DEVICES=0 trl vllm-serve \
|
| 174 |
+
--model Qwen/Qwen2.5-1.5B-Instruct \
|
| 175 |
+
--max-model-len 16384 \
|
| 176 |
+
--host 0.0.0.0 \
|
| 177 |
+
--port 8000
|
| 178 |
+
```
|
| 179 |
+
|
| 180 |
+
1. **Run Training on GPU 1** (Terminal 3)
|
| 181 |
+
|
| 182 |
+
```bash
|
| 183 |
+
source trl/.venv/bin/activate
|
| 184 |
+
cd trl/examples/scripts/nemo_gym
|
| 185 |
+
export WANDB_API_KEY=...
|
| 186 |
+
uv add omegaconf
|
| 187 |
+
|
| 188 |
+
CUDA_VISIBLE_DEVICES=1 python train_multi_environment.py --config config.yaml
|
| 189 |
+
```
|
| 190 |
+
|
| 191 |
+
## Multi-Node Training with Slurm
|
| 192 |
+
|
| 193 |
+
An example five-node training script is provided in `submit.sh`. Nodes one through four run the training algorithm, while node five runs vLLM inference for NeMo Gym agent rollouts.
|
| 194 |
+
|
| 195 |
+
1. **Configure the Script**
|
| 196 |
+
|
| 197 |
+
Update `submit.sh` with your Slurm account, partition, paths to your project directory, and updated training configs.
|
| 198 |
+
|
| 199 |
+
1. **Submit the Job**
|
| 200 |
+
|
| 201 |
+
```bash
|
| 202 |
+
sbatch submit.sh
|
| 203 |
+
```
|
| 204 |
+
|
| 205 |
+
1. **Monitor Training**
|
| 206 |
+
|
| 207 |
+
```bash
|
| 208 |
+
tail -f logs/<job_id>/*
|
| 209 |
+
```
|
| 210 |
+
|
| 211 |
+
> **Tip**: Set up wandb logging for detailed training metrics. For more details on TRL's vLLM integration, refer to the vLLM integration page.
|
| 212 |
+
|
| 213 |
+
## Multi-Environment Training
|
| 214 |
+
|
| 215 |
+
Train on multiple NeMo Gym environments simultaneously. This allows learning diverse capabilities, such as tool calling and math reasoning, in a single training run.
|
| 216 |
+
|
| 217 |
+
1. **Prepare Individual Datasets**
|
| 218 |
+
|
| 219 |
+
Prepare datasets for each environment. The workplace assistant dataset was prepared above. Now lets create a dataset for the mini sudoku environment implemented by the reasoning gym resources server in NeMo Gym:
|
| 220 |
+
|
| 221 |
+
```bash
|
| 222 |
+
cd Gym
|
| 223 |
+
source .venv/bin/activate
|
| 224 |
+
uv add reasoning-gym
|
| 225 |
+
cd resources_servers/reasoning_gym
|
| 226 |
+
python scripts/create_dataset.py \
|
| 227 |
+
--task mini_sudoku \
|
| 228 |
+
--size 2000 \
|
| 229 |
+
--seed 42 \
|
| 230 |
+
--output data/reasoning_gym/train_mini_sudoku.jsonl
|
| 231 |
+
|
| 232 |
+
python scripts/create_dataset.py \
|
| 233 |
+
--task mini_sudoku \
|
| 234 |
+
--size 50 \
|
| 235 |
+
--seed 24 \
|
| 236 |
+
--output data/reasoning_gym/val_mini_sudoku.jsonl
|
| 237 |
+
```
|
| 238 |
+
|
| 239 |
+
1. **Create Combined Dataset**
|
| 240 |
+
|
| 241 |
+
Combine datasets into a single file with tasks from both environments:
|
| 242 |
+
|
| 243 |
+
```bash
|
| 244 |
+
cat data/workplace_assistant/train_workplace.jsonl data/reasoning_gym/train_mini_sudoku.jsonl | shuf > train_multi_env.jsonl
|
| 245 |
+
```
|
| 246 |
+
|
| 247 |
+
> **Tip**: Ensure datasets are the same size before shuffling for an even blend of tasks. Repeat for the validation dataset.
|
| 248 |
+
|
| 249 |
+
1. **Update Training Config**
|
| 250 |
+
|
| 251 |
+
Update the config to point to the combined dataset:
|
| 252 |
+
|
| 253 |
+
```yaml
|
| 254 |
+
model_name: "Qwen/Qwen3-4B-Instruct-2507"
|
| 255 |
+
|
| 256 |
+
dataset_path: "/path/to/data/train_multi_env.jsonl"
|
| 257 |
+
eval_dataset_path: "/path/to/data/val_multi_env.jsonl"
|
| 258 |
+
|
| 259 |
+
task: "workplace-sudoku" # used in wandb run name
|
| 260 |
+
output_dir: "outputs/nemo_gym_multi_env"
|
| 261 |
+
|
| 262 |
+
# ... rest of config same
|
| 263 |
+
```
|
| 264 |
+
|
| 265 |
+
1. **Update ng_run**
|
| 266 |
+
|
| 267 |
+
Whether training interactively or via Slurm, update the `ng_run` command to include config files from each resources server:
|
| 268 |
+
|
| 269 |
+
```bash
|
| 270 |
+
cd Gym
|
| 271 |
+
source .venv/bin/activate
|
| 272 |
+
|
| 273 |
+
config_paths="responses_api_models/vllm_model/configs/vllm_model.yaml,\
|
| 274 |
+
resources_servers/workplace_assistant/configs/workplace_assistant.yaml,\
|
| 275 |
+
resources_servers/reasoning_gym/configs/reasoning_gym.yaml"
|
| 276 |
+
|
| 277 |
+
ng_run "+config_paths=[${config_paths}]"
|
| 278 |
+
```
|
| 279 |
+
|
| 280 |
+
This starts servers for both environments. The training script automatically routes each example to the correct agent server based on its `agent_ref` field.
|
| 281 |
+
|
| 282 |
+
1. **Run Training**
|
| 283 |
+
|
| 284 |
+
Update the Slurm submission script to use the new training config and both `ng_run` resources server configs, then submit the job as before.
|
| 285 |
+
|
| 286 |
+
The training script reads `agent_ref` from each example's metadata, routes requests to the correct NeMo Gym agent server, and handles different agents and environments in the same batch.
|
| 287 |
+
|
| 288 |
+
## Resources
|
| 289 |
+
|
| 290 |
+
- [NeMo Gym GitHub](https://github.com/NVIDIA-NeMo/Gym)
|
| 291 |
+
- [NeMo Gym Documentation](https://docs.nvidia.com/nemo/gym/latest/)
|
| 292 |
+
- [Training Script](https://github.com/huggingface/trl/blob/main/examples/scripts/nemo_gym/train_multi_environment.py)
|
| 293 |
+
- [TRL GRPO Trainer](grpo_trainer)
|
tasks/tasksmith-1c108f674e97/tests/source/docs/source/online_dpo_trainer.md
ADDED
|
@@ -0,0 +1,206 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Online DPO Trainer
|
| 2 |
+
|
| 3 |
+
[](https://huggingface.co/models?other=online-dpo,trl)
|
| 4 |
+
|
| 5 |
+
## Overview
|
| 6 |
+
|
| 7 |
+
Online DPO was proposed in [Direct Language Model Alignment from Online AI Feedback](https://huggingface.co/papers/2402.04792) by Shangmin Guo, Biao Zhang, Tianlin Liu, Tianqi Liu, Misha Khalman, Felipe Llinares, Alexandre Rame, Thomas Mesnard, Yao Zhao, Bilal Piot, Johan Ferret, and Mathieu Blondel.
|
| 8 |
+
|
| 9 |
+
The abstract from the paper is the following:
|
| 10 |
+
|
| 11 |
+
> Direct alignment from preferences (DAP) methods, such as DPO, have recently emerged as efficient alternatives to reinforcement learning from human feedback (RLHF), that do not require a separate reward model. However, the preference datasets used in DAP methods are usually collected ahead of training and never updated, thus the feedback is purely offline. Moreover, responses in these datasets are often sampled from a language model distinct from the one being aligned, and since the model evolves over training, the alignment phase is inevitably off-policy. In this study, we posit that online feedback is key and improves DAP methods. Our method, online AI feedback (OAIF), uses an LLM as annotator: on each training iteration, we sample two responses from the current model and prompt the LLM annotator to choose which one is preferred, thus providing online feedback. Despite its simplicity, we demonstrate via human evaluation in several tasks that OAIF outperforms both offline DAP and RLHF methods. We further show that the feedback leveraged in OAIF is easily controllable, via instruction prompts to the LLM annotator.
|
| 12 |
+
|
| 13 |
+
This post-training method was contributed by [Michael Noukhovitch](https://huggingface.co/mnoukhov), [Shengyi Costa Huang](https://huggingface.co/vwxyzjn), [Quentin Gallouédec](https://huggingface.co/qgallouedec), and [Edward Beeching](https://huggingface.co/edbeeching).
|
| 14 |
+
|
| 15 |
+
## Quick start
|
| 16 |
+
|
| 17 |
+
This example demonstrates how to train a model using the online DPO method. We use the [Qwen 0.5B model](https://huggingface.co/Qwen/Qwen2-0.5B-Instruct) as the base model and the [trl-lib/Qwen2-0.5B-Reward](https://huggingface.co/trl-lib/Qwen2-0.5B-Reward) reward model. We use the prompts from the [UltraFeedback dataset](https://huggingface.co/datasets/openbmb/UltraFeedback). You can view the prompts in the dataset here:
|
| 18 |
+
|
| 19 |
+
<iframe
|
| 20 |
+
src="https://huggingface.co/datasets/trl-lib/ultrafeedback-prompt/embed/viewer/default/train?row=0"
|
| 21 |
+
frameborder="0"
|
| 22 |
+
width="100%"
|
| 23 |
+
height="560px"
|
| 24 |
+
></iframe>
|
| 25 |
+
|
| 26 |
+
Below is the script to train the model:
|
| 27 |
+
|
| 28 |
+
```python
|
| 29 |
+
# train_online_dpo.py
|
| 30 |
+
from datasets import load_dataset
|
| 31 |
+
from trl.experimental.online_dpo import OnlineDPOConfig, OnlineDPOTrainer
|
| 32 |
+
from transformers import AutoModelForCausalLM, AutoModelForSequenceClassification, AutoTokenizer
|
| 33 |
+
|
| 34 |
+
model = AutoModelForCausalLM.from_pretrained("Qwen/Qwen2-0.5B-Instruct")
|
| 35 |
+
tokenizer = AutoTokenizer.from_pretrained("Qwen/Qwen2-0.5B-Instruct")
|
| 36 |
+
reward_model = AutoModelForSequenceClassification.from_pretrained("trl-lib/Qwen2-0.5B-Reward", num_labels=1)
|
| 37 |
+
train_dataset = load_dataset("trl-lib/ultrafeedback-prompt", split="train")
|
| 38 |
+
|
| 39 |
+
training_args = OnlineDPOConfig(output_dir="Qwen2-0.5B-OnlineDPO")
|
| 40 |
+
trainer = OnlineDPOTrainer(
|
| 41 |
+
model=model, reward_funcs=reward_model, args=training_args, processing_class=tokenizer, train_dataset=train_dataset
|
| 42 |
+
)
|
| 43 |
+
trainer.train()
|
| 44 |
+
```
|
| 45 |
+
|
| 46 |
+
Execute the script using the following command:
|
| 47 |
+
|
| 48 |
+
```bash
|
| 49 |
+
accelerate launch train_online_dpo.py
|
| 50 |
+
```
|
| 51 |
+
|
| 52 |
+
Distributed across 8 GPUs, the training takes approximately 1 hour. You can verify the training progress by checking the reward graph. An increasing trend in both the reward for rejected and chosen completions indicates that the model is improving and generating better responses over time.
|
| 53 |
+
|
| 54 |
+

|
| 55 |
+
|
| 56 |
+
To see how the [trained model](https://huggingface.co/trl-lib/Qwen2-0.5B-OnlineDPO) performs, you can use the [Transformers Chat CLI](https://huggingface.co/docs/transformers/quicktour#chat-with-text-generation-models).
|
| 57 |
+
|
| 58 |
+
<pre><code>$ transformers chat trl-lib/Qwen2-0.5B-OnlineDPO
|
| 59 |
+
<strong><span style="color: red;"><quentin_gallouedec>:</span></strong>
|
| 60 |
+
What is the best programming language?
|
| 61 |
+
|
| 62 |
+
<strong><span style="color: blue;"><trl-lib/Qwen2-0.5B-OnlineDPO>:</span></strong>
|
| 63 |
+
The best programming language depends on your specific needs and priorities. Some people prefer imperative programming languages (like Haskell or Lisp), while others prefer functional programming languages (like Scala or Python). It's important to consider your work style, programming environment, and project requirements when choosing a programming language.
|
| 64 |
+
</code></pre>
|
| 65 |
+
|
| 66 |
+
## Expected dataset type
|
| 67 |
+
|
| 68 |
+
Online DPO only requires a [prompt-only dataset](dataset_formats#prompt-only) (unlike offline DPO, that expects [preference dataset](dataset_formats#preference)). The [`experimental.online_dpo.OnlineDPOTrainer`] supports both [conversational](dataset_formats#conversational) and [standard](dataset_formats#standard) dataset formats. When provided with a conversational dataset, the trainer will automatically apply the chat template to the dataset.
|
| 69 |
+
|
| 70 |
+
## Usage tips
|
| 71 |
+
|
| 72 |
+
### Encourage EOS token generation
|
| 73 |
+
|
| 74 |
+
When using a reward model, we may want the model to generate completions within a given length. During training, the model will generate completions up to the maximum length specified in the `max_new_tokens` argument of [`experimental.online_dpo.OnlineDPOConfig`]. If you want to penalize the model for not generating an EOS token before reaching the maximum length, you can use the `missing_eos_penalty` argument of [`experimental.online_dpo.OnlineDPOConfig`]:
|
| 75 |
+
|
| 76 |
+
```python
|
| 77 |
+
training_args = OnlineDPOConfig(..., max_new_tokens=128, missing_eos_penalty=1.0)
|
| 78 |
+
```
|
| 79 |
+
|
| 80 |
+
### Logging Completions
|
| 81 |
+
|
| 82 |
+
To better understand your model's behavior during training, you can log sample completions periodically using the [`LogCompletionsCallback`].
|
| 83 |
+
|
| 84 |
+
```python
|
| 85 |
+
trainer = OnlineDPOTrainer(..., eval_dataset=eval_dataset)
|
| 86 |
+
completions_callback = LogCompletionsCallback(trainer, num_prompts=8)
|
| 87 |
+
trainer.add_callback(completions_callback)
|
| 88 |
+
```
|
| 89 |
+
|
| 90 |
+
This callback logs the model's generated completions directly to Weights & Biases.
|
| 91 |
+
|
| 92 |
+

|
| 93 |
+
|
| 94 |
+
## Example script
|
| 95 |
+
|
| 96 |
+
We provide an example script to train a model using the online DPO method. The script is available in [`examples/scripts/dpo_online.py`](https://github.com/huggingface/trl/blob/main/examples/scripts/dpo_online.py)
|
| 97 |
+
|
| 98 |
+
To test the online DPO script with the [Qwen2.5 0.5B model](https://huggingface.co/trl-lib/Qwen/Qwen2.5-0.5B-Instruct) on the [UltraFeedback dataset](https://huggingface.co/datasets/openbmb/UltraFeedback), run the following command:
|
| 99 |
+
|
| 100 |
+
```bash
|
| 101 |
+
python examples/scripts/dpo_online.py \
|
| 102 |
+
--model_name_or_path Qwen/Qwen2.5-0.5B-Instruct \
|
| 103 |
+
--reward_model_path trl-lib/Qwen2-0.5B-Reward \
|
| 104 |
+
--dataset_name trl-lib/ultrafeedback-prompt \
|
| 105 |
+
--learning_rate 5.0e-7 \
|
| 106 |
+
--output_dir Qwen2.5-0.5B-Online-DPO \
|
| 107 |
+
--warmup_steps 0.1 \
|
| 108 |
+
--push_to_hub
|
| 109 |
+
```
|
| 110 |
+
|
| 111 |
+
## Logged metrics
|
| 112 |
+
|
| 113 |
+
While training and evaluating, we record the following reward metrics. Here is an example [tracked run at Weights and Biases](https://wandb.ai/huggingface/trl/runs/w4apmsi9)
|
| 114 |
+
|
| 115 |
+
* `objective/kl`: The mean Kullback-Leibler (KL) divergence between the current model and reference model.
|
| 116 |
+
* `objective/entropy`: The mean entropy of the model, indicating the randomness of the actions chosen by the model.
|
| 117 |
+
* `objective/non_score_reward`: The mean reward from non-score-related sources, basically `beta * kl.sum(1)`, where `beta` is the KL penalty coefficient and `kl` is the per-token KL divergence.
|
| 118 |
+
* `objective/rlhf_reward`: The mean RLHF reward, which is `scores - non_score_reward`. The `rlhf_reward` is the ultimate objective of online DPO training. If training works as intended, this metric should keep going up.
|
| 119 |
+
* `objective/scores`: The mean scores returned by the reward model.
|
| 120 |
+
* `objective/scores_margin`: The mean score margin (according to the external reward model) between the chosen and rejected completions.
|
| 121 |
+
* `rewards/chosen`: The mean reward (according to online DPO's implicit reward model)of the chosen completions.
|
| 122 |
+
* `rewards/rejected`: The mean reward (according to online DPO's implicit reward model) of the rejected completions.
|
| 123 |
+
* `rewards/accuracies`: The accuracies of the online DPO's implicit reward model.
|
| 124 |
+
* `rewards/margins`: The mean reward margin (according to online DPO's implicit reward model) between the chosen and rejected completions.
|
| 125 |
+
* `logps/chosen`: The mean log probabilities of the chosen completions.
|
| 126 |
+
* `logps/rejected`: The mean log probabilities of the rejected completions.
|
| 127 |
+
* `val/contain_eos_token`: The fraction of completions which contain an EOS token.
|
| 128 |
+
* `beta`: The parameter that controls the weight of the loss term representing the deviation from the reference model. Typically fixed, but can be made dynamic by passing a list to [`experimental.online_dpo.OnlineDPOConfig`].
|
| 129 |
+
|
| 130 |
+
## Benchmark experiments
|
| 131 |
+
|
| 132 |
+
To validate the online DPO implementation works, we ran experiments with the Pythia 1B, 2.8B, and 6.9B models on a single node of 8 x H100s. Here are the commands we used to run the experiments. We take the SFT / RM models directly from [The N+ Implementation Details of RLHF with PPO: A Case Study on TL;DR Summarization](https://huggingface.co/papers/2403.17031).
|
| 133 |
+
|
| 134 |
+
```shell
|
| 135 |
+
# 1B Online DPO experiment
|
| 136 |
+
accelerate launch --config_file examples/accelerate_configs/multi_gpu.yaml \
|
| 137 |
+
examples/scripts/dpo_online.py \
|
| 138 |
+
--model_name_or_path trl-lib/pythia-1b-deduped-tldr-sft \
|
| 139 |
+
--reward_model_path trl-lib/pythia-1b-deduped-tldr-rm \
|
| 140 |
+
--dataset_name trl-lib/tldr \
|
| 141 |
+
--learning_rate 5.0e-7 \
|
| 142 |
+
--output_dir pythia-1b-deduped-tldr-online-dpo \
|
| 143 |
+
--beta 0.1 \
|
| 144 |
+
--per_device_train_batch_size 8 \
|
| 145 |
+
--gradient_accumulation_steps 2 \
|
| 146 |
+
--num_train_epochs 3 \
|
| 147 |
+
--max_new_tokens 53 \
|
| 148 |
+
--warmup_steps 0.1 \
|
| 149 |
+
--missing_eos_penalty 1.0 \
|
| 150 |
+
--save_steps 0.1 \
|
| 151 |
+
--push_to_hub
|
| 152 |
+
|
| 153 |
+
# 2.8B Online DPO experiment
|
| 154 |
+
accelerate launch --config_file examples/accelerate_configs/deepspeed_zero2.yaml \
|
| 155 |
+
examples/scripts/dpo_online.py \
|
| 156 |
+
--model_name_or_path trl-lib/pythia-2.8b-deduped-tldr-sft \
|
| 157 |
+
--reward_model_path trl-lib/pythia-2.8b-deduped-tldr-rm \
|
| 158 |
+
--dataset_name trl-lib/tldr \
|
| 159 |
+
--learning_rate 5.0e-7 \
|
| 160 |
+
--output_dir pythia-2.8b-deduped-tldr-online-dpo \
|
| 161 |
+
--beta 0.1 \
|
| 162 |
+
--per_device_train_batch_size 8 \
|
| 163 |
+
--gradient_accumulation_steps 2 \
|
| 164 |
+
--num_train_epochs 3 \
|
| 165 |
+
--max_new_tokens 53 \
|
| 166 |
+
--warmup_steps 0.1 \
|
| 167 |
+
--missing_eos_penalty 1.0 \
|
| 168 |
+
--save_steps 0.1 \
|
| 169 |
+
--push_to_hub
|
| 170 |
+
|
| 171 |
+
# 6.9B Online DPO experiment
|
| 172 |
+
accelerate launch --config_file examples/accelerate_configs/deepspeed_zero2.yaml \
|
| 173 |
+
examples/scripts/dpo_online.py \
|
| 174 |
+
--model_name_or_path trl-lib/pythia-6.9b-deduped-tldr-sft \
|
| 175 |
+
--reward_model_path trl-lib/pythia-6.9b-deduped-tldr-rm \
|
| 176 |
+
--dataset_name trl-lib/tldr \
|
| 177 |
+
--learning_rate 5.0e-7 \
|
| 178 |
+
--output_dir pythia-6.9b-deduped-tldr-online-dpo \
|
| 179 |
+
--beta 0.1 \
|
| 180 |
+
--per_device_train_batch_size 4 \
|
| 181 |
+
--gradient_accumulation_steps 4 \
|
| 182 |
+
--num_train_epochs 3 \
|
| 183 |
+
--max_new_tokens 53 \
|
| 184 |
+
--warmup_steps 0.1 \
|
| 185 |
+
--missing_eos_penalty 1.0 \
|
| 186 |
+
--save_steps 0.1 \
|
| 187 |
+
--push_to_hub
|
| 188 |
+
```
|
| 189 |
+
|
| 190 |
+
Checkpoints and experiment tracking are available at:
|
| 191 |
+
|
| 192 |
+
* [🤗 Model checkpoints](https://huggingface.co/collections/trl-lib/online-dpo-66acd3fa38a331a9cd457b07)
|
| 193 |
+
* [🐝 Tracked experiment](https://wandb.ai/huggingface/trl/reports/Online-DPO-experiments-for-TL-DR-summarisation--Vmlldzo5MTczMDU0)
|
| 194 |
+
|
| 195 |
+
The online DPO checkpoint gets increasingly more win rate as we scale up the model sizes. This is a good sign that the online DPO implementation is working as intended.
|
| 196 |
+
|
| 197 |
+
## OnlineDPOTrainer
|
| 198 |
+
|
| 199 |
+
[[autodoc]] experimental.online_dpo.OnlineDPOTrainer
|
| 200 |
+
- train
|
| 201 |
+
- save_model
|
| 202 |
+
- push_to_hub
|
| 203 |
+
|
| 204 |
+
## OnlineDPOConfig
|
| 205 |
+
|
| 206 |
+
[[autodoc]] experimental.online_dpo.OnlineDPOConfig
|
tasks/tasksmith-1c108f674e97/tests/source/docs/source/openenv.md
ADDED
|
@@ -0,0 +1,659 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# OpenEnv Integration for Training LLMs with Environments
|
| 2 |
+
|
| 3 |
+
[OpenEnv](https://github.com/meta-pytorch/OpenEnv) is an open-source framework for defining, deploying, and interacting with environments in reinforcement learning (RL) and agentic workflows. It provides standardized APIs for environment interaction and supports running environments as backend servers (via WebSocket or containerised execution). You can find a collection of ready-to-use OpenEnv environments on the [Hugging Face Hub](https://huggingface.co/collections/openenv/openenv-environment-hub).
|
| 4 |
+
|
| 5 |
+
This guide covers **how to integrate OpenEnv with TRL**. For more on OpenEnv itself, see the [OpenEnv docs](https://meta-pytorch.org/OpenEnv/).
|
| 6 |
+
|
| 7 |
+
> [!NOTE]
|
| 8 |
+
> You can explore ready-to-use example [scripts](example_overview#openenv-scripts) and [notebooks](example_overview#openenv-notebooks) in the Examples Overview.
|
| 9 |
+
|
| 10 |
+
## When to use environments
|
| 11 |
+
|
| 12 |
+
[`GRPOTrainer`] can be used to train agents. For agentic tasks, it supports two modes: **tools**, where the model can call external functions but each call is stateless and independent, and **environments**, which maintain state across turns, enabling genuine multi-turn interaction where the agent's actions shape future observations. Use environments when continuity matters — for example, navigating a game, browsing a web page, or any task where what the agent sees next depends on what it did before.
|
| 13 |
+
|
| 14 |
+
## Installation
|
| 15 |
+
|
| 16 |
+
OpenEnv environments are hosted as Hugging Face Spaces, which are also pip-installable Git repositories:
|
| 17 |
+
|
| 18 |
+
```bash
|
| 19 |
+
# Echo environment
|
| 20 |
+
pip install "openenv-echo-env @ git+https://huggingface.co/spaces/openenv/echo_env"
|
| 21 |
+
|
| 22 |
+
# Wordle (TextArena) environment
|
| 23 |
+
pip install "openenv-textarena @ git+https://huggingface.co/spaces/openenv/wordle"
|
| 24 |
+
|
| 25 |
+
# Catch (OpenSpiel) environment
|
| 26 |
+
pip install "openenv-openspiel-env @ git+https://huggingface.co/spaces/openenv/openspiel_env"
|
| 27 |
+
```
|
| 28 |
+
|
| 29 |
+
This installs the **environment client** (e.g., `EchoEnv`) that communicates with the remote environment server via WebSocket, along with the action/observation models and all required dependencies (including `openenv-core`).
|
| 30 |
+
|
| 31 |
+
> [!TIP]
|
| 32 |
+
> You can find the install command for any environment on its HF Space page. Click the **⋮ (three dots)** menu and select **"Use this Space"** to see the install instructions.
|
| 33 |
+
|
| 34 |
+
> [!TIP]
|
| 35 |
+
> You can also install the core package from PyPI with `pip install "openenv-core[core]>=0.2.1"`, but note that environment-specific dependencies may need to be installed separately.
|
| 36 |
+
|
| 37 |
+
For development, you can clone the OpenEnv repo and install locally:
|
| 38 |
+
|
| 39 |
+
```bash
|
| 40 |
+
git clone https://github.com/meta-pytorch/OpenEnv.git
|
| 41 |
+
cd OpenEnv/envs/echo_env
|
| 42 |
+
pip install -e .
|
| 43 |
+
```
|
| 44 |
+
|
| 45 |
+
> [!NOTE]
|
| 46 |
+
> Each environment script in TRL includes inline dependency metadata (PEP 723) so you can also run them directly with [uv](https://docs.astral.sh/uv/):
|
| 47 |
+
>
|
| 48 |
+
> ```bash
|
| 49 |
+
> uv run examples/scripts/openenv/echo.py
|
| 50 |
+
> ```
|
| 51 |
+
>
|
| 52 |
+
> This automatically installs the required environment package in an isolated virtual environment.
|
| 53 |
+
|
| 54 |
+
## Quick start
|
| 55 |
+
|
| 56 |
+
The fastest way to understand the integration is a complete example. The [echo.py](https://github.com/huggingface/trl/blob/main/examples/scripts/openenv/echo.py) script trains a model with the [Echo environment](https://meta-pytorch.org/OpenEnv/environments/echo.html), which rewards completions based on their text length:
|
| 57 |
+
|
| 58 |
+
```python
|
| 59 |
+
from datasets import Dataset
|
| 60 |
+
from echo_env import EchoEnv
|
| 61 |
+
from echo_env.models import EchoAction
|
| 62 |
+
|
| 63 |
+
from trl import GRPOConfig, GRPOTrainer
|
| 64 |
+
|
| 65 |
+
ENV_URL = "https://openenv-echo-env.hf.space"
|
| 66 |
+
|
| 67 |
+
class EchoToolEnv:
|
| 68 |
+
def __init__(self):
|
| 69 |
+
self.env = EchoEnv(base_url=ENV_URL)
|
| 70 |
+
self.reward = 0.0
|
| 71 |
+
|
| 72 |
+
def reset(self, **kwargs) -> str | None:
|
| 73 |
+
self.reward = 0.0
|
| 74 |
+
return None
|
| 75 |
+
|
| 76 |
+
def echo(self, message: str) -> str:
|
| 77 |
+
"""
|
| 78 |
+
Echo the message back from the environment.
|
| 79 |
+
|
| 80 |
+
Args:
|
| 81 |
+
message: The message to echo
|
| 82 |
+
|
| 83 |
+
Returns:
|
| 84 |
+
The echoed message.
|
| 85 |
+
"""
|
| 86 |
+
observation = self.env.step(EchoAction(message=message))
|
| 87 |
+
self.reward = observation.observation.reward
|
| 88 |
+
return observation.observation.echoed_message
|
| 89 |
+
|
| 90 |
+
def reward_func(environments, **kwargs):
|
| 91 |
+
return [env.reward for env in environments]
|
| 92 |
+
|
| 93 |
+
dataset = Dataset.from_dict(
|
| 94 |
+
{"prompt": [[{"role": "user", "content": "Try to echo 'Hello World!' in the environment."}]] * 64}
|
| 95 |
+
)
|
| 96 |
+
|
| 97 |
+
trainer = GRPOTrainer(
|
| 98 |
+
model="Qwen/Qwen3-0.6B",
|
| 99 |
+
train_dataset=dataset,
|
| 100 |
+
reward_funcs=reward_func,
|
| 101 |
+
args=GRPOConfig(
|
| 102 |
+
chat_template_kwargs={"enable_thinking": False},
|
| 103 |
+
log_completions=True,
|
| 104 |
+
),
|
| 105 |
+
environment_factory=EchoToolEnv,
|
| 106 |
+
)
|
| 107 |
+
trainer.train()
|
| 108 |
+
```
|
| 109 |
+
|
| 110 |
+
That's it. Here's what happens under the hood:
|
| 111 |
+
|
| 112 |
+
1. **`environment_factory=EchoToolEnv`**: The trainer creates one `EchoToolEnv` instance per generation (pass the class, not an instance).
|
| 113 |
+
2. **`reset()`** is called at the start of each episode to initialize state. Returns an observation string (or `None`).
|
| 114 |
+
3. **Tool discovery**: The trainer discovers all public methods on the environment instance (here, `echo()`) and exposes them as function-calling tools. Each method must have a proper docstring with typed arguments, which the trainer uses to build the tool schema.
|
| 115 |
+
4. **Multi-turn loop**: The trainer generates a completion, parses tool calls, executes `echo()`, appends the result, and generates again, until the model stops calling tools or `max_completion_length` is reached.
|
| 116 |
+
5. **Reward function**: Reads `env.reward` from each environment instance after the episode (before the environment is reset).
|
| 117 |
+
|
| 118 |
+
```bash
|
| 119 |
+
# Run the example
|
| 120 |
+
python examples/scripts/openenv/echo.py
|
| 121 |
+
|
| 122 |
+
# Customize model and environment URL
|
| 123 |
+
python examples/scripts/openenv/echo.py --model Qwen/Qwen3-0.6B --env-host https://openenv-echo-env.hf.space
|
| 124 |
+
```
|
| 125 |
+
|
| 126 |
+
Below is the reward curve from training:
|
| 127 |
+
|
| 128 |
+
<iframe src="https://trl-lib-trackio.hf.space?project=openenv&metrics=train/rewards/reward_from_env/mean&runs=qgallouedec-1761202871&sidebar=hidden&navbar=hidden" style="width:100%; max-width:800px; height:500px; border:0;"></iframe>
|
| 129 |
+
|
| 130 |
+
> [!NOTE]
|
| 131 |
+
> You can explore more ready-to-use example [scripts](example_overview#openenv-scripts) and [notebooks](example_overview#openenv-notebooks) in the Examples Overview.
|
| 132 |
+
|
| 133 |
+
## How `environment_factory` works
|
| 134 |
+
|
| 135 |
+
TRL's [`GRPOTrainer`] supports interactive environment training through the `environment_factory` argument. When provided, the trainer automatically handles the multi-turn tool-calling loop: it generates completions, parses tool calls, executes them against the environment, and feeds the results back to the model. All without custom rollout code.
|
| 136 |
+
|
| 137 |
+
### Environment class requirements
|
| 138 |
+
|
| 139 |
+
Your environment class must follow these rules:
|
| 140 |
+
|
| 141 |
+
- **`__init__(self)`** *(optional)*: If provided, must take no arguments. Use it to initialize state or clients. If you need external configuration (e.g., a URL), capture it from the enclosing scope or module-level variables.
|
| 142 |
+
- **`reset(self, **kwargs)`**: Called at the start of each episode. Receives all dataset columns as keyword arguments. Return a string observation (or `None` for no initial observation).
|
| 143 |
+
- **Tool methods**: Any public method (not starting with `_`) other than `reset` is automatically exposed as a tool. Each tool method must have a docstring with `Args:` descriptions, since the trainer uses these to generate the tool schema for the model.
|
| 144 |
+
|
| 145 |
+
### Tips for environment classes
|
| 146 |
+
|
| 147 |
+
- **State for reward**: You can store any state you want on the environment instance (e.g., `self.reward`, `self.done`, etc.) and access it in your reward function via the `environments` parameter. Refer to the [Quick Start guide](#quick-start) for an example of this pattern.
|
| 148 |
+
- **Error handling**: If a tool method raises an exception (e.g., `ValueError("Game over.")`), the trainer catches it and feeds the error message back to the model as a tool response. This is the recommended way to signal that an action is invalid or that the episode has ended.
|
| 149 |
+
|
| 150 |
+
```python
|
| 151 |
+
ENV_URL = "https://my-env.hf.space"
|
| 152 |
+
|
| 153 |
+
class MyEnv:
|
| 154 |
+
def __init__(self):
|
| 155 |
+
self.client = MyClient(base_url=ENV_URL) # captured from enclosing scope
|
| 156 |
+
self.reward = 0.0
|
| 157 |
+
|
| 158 |
+
def reset(self, **kwargs) -> str | None:
|
| 159 |
+
self.reward = 0.0
|
| 160 |
+
return "Initial observation for the model"
|
| 161 |
+
|
| 162 |
+
def my_tool(self, arg1: str, arg2: int) -> str:
|
| 163 |
+
"""
|
| 164 |
+
Description of what this tool does.
|
| 165 |
+
|
| 166 |
+
Args:
|
| 167 |
+
arg1: Description of arg1
|
| 168 |
+
arg2: Description of arg2
|
| 169 |
+
|
| 170 |
+
Returns:
|
| 171 |
+
The result message.
|
| 172 |
+
"""
|
| 173 |
+
self.reward = 1.0
|
| 174 |
+
return "Tool result"
|
| 175 |
+
```
|
| 176 |
+
|
| 177 |
+
> [!IMPORTANT]
|
| 178 |
+
> Tools must be **individual methods** with descriptive names and typed arguments (e.g., `guess(word: str)`, `move(direction: str)`). We do not recommend using generic methods like `step(action)`, since the model needs meaningful tool names and argument descriptions to learn tool calling.
|
| 179 |
+
|
| 180 |
+
### Reward functions
|
| 181 |
+
|
| 182 |
+
Reward functions receive the `environments` parameter (a list of environment instances), so you can access any state stored during the episode:
|
| 183 |
+
|
| 184 |
+
```python
|
| 185 |
+
def reward_func(environments, **kwargs) -> list[float]:
|
| 186 |
+
return [env.reward for env in environments]
|
| 187 |
+
```
|
| 188 |
+
|
| 189 |
+
For more information on reward functions, see the [GRPO - Custom Reward Functions](grpo_trainer#custom-reward-functions).
|
| 190 |
+
|
| 191 |
+
### Tips for reward functions
|
| 192 |
+
|
| 193 |
+
A few things we've found helpful when working with OpenEnv environments and GRPO:
|
| 194 |
+
|
| 195 |
+
- **Simple rewards work well.** In our experiments with Wordle and Sudoku, binary rewards (1.0 for success, 0.0 otherwise) gave cleaner training signals than shaped rewards with partial credit. GRPO compares completions within a group, so the relative ranking matters more than the absolute values.
|
| 196 |
+
- **Check the final state, not the path.** When possible, let the environment judge the outcome (e.g., "did the model solve the puzzle?") rather than checking if it followed a specific sequence of actions. This gives the model freedom to discover its own strategies.
|
| 197 |
+
- **Test your reward before training.** Run a few episodes manually (see the [Wordle example notebook](https://github.com/huggingface/trl/blob/main/examples/notebooks/openenv_wordle_grpo.ipynb)) to confirm the environment returns sensible rewards. If a capable model can't score higher than a random baseline, the reward signal may need adjustment.
|
| 198 |
+
|
| 199 |
+
### `max_completion_length` in multi-turn episodes
|
| 200 |
+
|
| 201 |
+
The `max_completion_length` parameter limits the **total number of tokens across the entire multi-turn conversation** (all model generations + tool results combined), not just a single generation. For environments with many turns (e.g., Sudoku with dozens of moves), you may need to increase it:
|
| 202 |
+
|
| 203 |
+
```python
|
| 204 |
+
args = GRPOConfig(
|
| 205 |
+
max_completion_length=4096, # default is usually 256-1024, increase for long episodes
|
| 206 |
+
# ...
|
| 207 |
+
)
|
| 208 |
+
```
|
| 209 |
+
|
| 210 |
+
If episodes are being cut short (model stops mid-game), this is likely the cause.
|
| 211 |
+
|
| 212 |
+
## Advanced example: Wordle
|
| 213 |
+
|
| 214 |
+
Let's train a model to play [Wordle](https://www.nytimes.com/games/wordle/index.html) using the [`TextArena`](https://meta-pytorch.org/OpenEnv/environments/textarena.html) environment. This demonstrates multi-turn interaction, cumulative feedback handling, and episode termination via exceptions.
|
| 215 |
+
|
| 216 |
+
> [!NOTE]
|
| 217 |
+
> You can explore the notebook version of this example in [the OpenEnv Wordle GRPO example](https://github.com/huggingface/trl/blob/main/examples/notebooks/openenv_wordle_grpo.ipynb).
|
| 218 |
+
|
| 219 |
+
### The TextArena Environment
|
| 220 |
+
|
| 221 |
+
[TextArena](https://huggingface.co/papers/2504.11442) is an open-source collection of competitive text-based games designed to evaluate reasoning skills in LLMs using textual games like Wordle, Snake, Tic-Tac-Toe, and more.
|
| 222 |
+
|
| 223 |
+

|
| 224 |
+
|
| 225 |
+
### Why Wordle?
|
| 226 |
+
|
| 227 |
+
Wordle is a good benchmark for environment-based RL because it requires reasoning about feedback, is purely text-based, and models from 1B parameters can improve at it. Each guess is only 8 tokens, making it lightweight to experiment with.
|
| 228 |
+
|
| 229 |
+
> [!NOTE] How does Wordle work?
|
| 230 |
+
> Wordle is a word guessing game where the player has to guess a 5-letter word in 6 attempts. After each guess, the environment provides letter-by-letter feedback:
|
| 231 |
+
>
|
| 232 |
+
> ```
|
| 233 |
+
> G U E S S
|
| 234 |
+
> X G Y X X
|
| 235 |
+
> ```
|
| 236 |
+
> X = not in the word, G = correct position (green), Y = wrong position (yellow). Here, "U" is correct and in place, "E" is in the word but misplaced.
|
| 237 |
+
|
| 238 |
+
### Environment class
|
| 239 |
+
|
| 240 |
+
The `WordleEnv` class wraps the TextArena client and exposes `guess()` as the tool:
|
| 241 |
+
|
| 242 |
+
```python
|
| 243 |
+
from textarena_env import TextArenaAction, TextArenaEnv
|
| 244 |
+
|
| 245 |
+
class WordleEnv:
|
| 246 |
+
def __init__(self):
|
| 247 |
+
self.client = TextArenaEnv(base_url="https://openenv-wordle.hf.space")
|
| 248 |
+
|
| 249 |
+
def reset(self, **kwargs) -> str | None:
|
| 250 |
+
result = self.client.reset()
|
| 251 |
+
self._last_full_feedback = result.observation.messages[0].content
|
| 252 |
+
self.reward = 0.0
|
| 253 |
+
self.done = False
|
| 254 |
+
return self._last_full_feedback
|
| 255 |
+
|
| 256 |
+
def guess(self, guess: str) -> str:
|
| 257 |
+
"""
|
| 258 |
+
Make a guess in the Wordle environment.
|
| 259 |
+
|
| 260 |
+
Args:
|
| 261 |
+
guess: The guessed word, formatted as '[abcde]'
|
| 262 |
+
|
| 263 |
+
Returns:
|
| 264 |
+
The feedback message from the environment.
|
| 265 |
+
"""
|
| 266 |
+
if self.done:
|
| 267 |
+
raise ValueError("Game over.")
|
| 268 |
+
result = self.client.step(TextArenaAction(message=guess))
|
| 269 |
+
_full_feedback = result.observation.messages[0].content
|
| 270 |
+
feedback = _full_feedback[len(self._last_full_feedback):]
|
| 271 |
+
self._last_full_feedback = _full_feedback
|
| 272 |
+
if "You attempted an invalid move" in feedback:
|
| 273 |
+
self.reward = 0.0
|
| 274 |
+
else:
|
| 275 |
+
self.reward = result.reward
|
| 276 |
+
self.done = result.done
|
| 277 |
+
return feedback
|
| 278 |
+
```
|
| 279 |
+
|
| 280 |
+
Key design choices:
|
| 281 |
+
|
| 282 |
+
- **`reset()`** returns the initial game message as the first observation the model sees.
|
| 283 |
+
- **`guess()`** is the only tool. The model calls it each turn with a 5-letter word.
|
| 284 |
+
- **Cumulative feedback slicing**: TextArena returns the full game history each turn. We slice out only the new part to avoid repeating context.
|
| 285 |
+
- **Exception on done**: If the model tries to guess after the game ends, `guess()` raises a `ValueError`. The trainer catches this and feeds `"Game over."` back to the model as a tool response. The model learns to stop calling tools after this signal.
|
| 286 |
+
|
| 287 |
+
### Reward function and training
|
| 288 |
+
|
| 289 |
+
```python
|
| 290 |
+
from datasets import Dataset
|
| 291 |
+
from trl import GRPOConfig, GRPOTrainer
|
| 292 |
+
|
| 293 |
+
def reward_func(environments, **kwargs) -> list[float]:
|
| 294 |
+
return [env.reward for env in environments]
|
| 295 |
+
|
| 296 |
+
prompt = """You are an expert Wordle solver with deep knowledge of English vocabulary...
|
| 297 |
+
Use the tool `guess` to make a guess."""
|
| 298 |
+
|
| 299 |
+
dataset = Dataset.from_dict({"prompt": [[{"role": "user", "content": prompt}]] * 1000})
|
| 300 |
+
|
| 301 |
+
trainer = GRPOTrainer(
|
| 302 |
+
model="Qwen/Qwen3-1.7B",
|
| 303 |
+
reward_funcs=reward_func,
|
| 304 |
+
train_dataset=dataset,
|
| 305 |
+
args=GRPOConfig(
|
| 306 |
+
use_vllm=True,
|
| 307 |
+
vllm_mode="colocate",
|
| 308 |
+
chat_template_kwargs={"enable_thinking": False},
|
| 309 |
+
max_completion_length=1024,
|
| 310 |
+
num_generations=4,
|
| 311 |
+
gradient_accumulation_steps=64,
|
| 312 |
+
),
|
| 313 |
+
environment_factory=WordleEnv,
|
| 314 |
+
)
|
| 315 |
+
trainer.train()
|
| 316 |
+
```
|
| 317 |
+
|
| 318 |
+
The environment returns `1.0` if the model wins and `0.0` otherwise.
|
| 319 |
+
|
| 320 |
+
### Running the example
|
| 321 |
+
|
| 322 |
+
<hfoptions id="wordle_vllm_mode">
|
| 323 |
+
|
| 324 |
+
<hfoption id="colocate">
|
| 325 |
+
|
| 326 |
+
**Colocate mode (1 GPU, recommended)**
|
| 327 |
+
|
| 328 |
+
```bash
|
| 329 |
+
python examples/scripts/openenv/wordle.py --vllm-mode colocate
|
| 330 |
+
```
|
| 331 |
+
|
| 332 |
+
This runs vLLM in the same process as training, requiring only a single GPU.
|
| 333 |
+
|
| 334 |
+
</hfoption>
|
| 335 |
+
|
| 336 |
+
<hfoption id="server">
|
| 337 |
+
|
| 338 |
+
**Server mode (2+ GPUs, scalable)**
|
| 339 |
+
|
| 340 |
+
```bash
|
| 341 |
+
# Terminal 1: Start vLLM inference server
|
| 342 |
+
CUDA_VISIBLE_DEVICES=0 trl vllm-serve --model Qwen/Qwen3-1.7B --host 0.0.0.0 --port 8000
|
| 343 |
+
|
| 344 |
+
# Terminal 2: Run GRPO training with OpenEnv
|
| 345 |
+
CUDA_VISIBLE_DEVICES=1 python examples/scripts/openenv/wordle.py --vllm-mode server --vllm-server-url http://localhost:8000
|
| 346 |
+
```
|
| 347 |
+
|
| 348 |
+
</hfoption>
|
| 349 |
+
|
| 350 |
+
</hfoptions>
|
| 351 |
+
|
| 352 |
+
### Results
|
| 353 |
+
|
| 354 |
+
The model improves its performance by reducing repetitions and increasing correct guesses. However, Qwen3-1.7B with `enable_thinking=False` is not able to consistently win the game.
|
| 355 |
+
|
| 356 |
+
<iframe src="https://burtenshaw-wordle-grpo.hf.space?project=group-Qwen-Qwen3-17B&metrics=reward&runs=run-2025-10-26_09-39-49,run-2025-10-26_08-04-49&sidebar=hidden&navbar=hidden" style="width:100%; max-width:800px; height:500px; border:0;"></iframe>
|
| 357 |
+
|
| 358 |
+
> [!NOTE]
|
| 359 |
+
> With `enable_thinking=False` (the default in these examples), small models like Qwen3-1.7B can learn to improve their guesses but should not be expected to consistently solve the game. For significantly better results, use larger models or enable thinking mode (`enable_thinking=True`), which allows the model to reason before making a guess at the cost of longer completions.
|
| 360 |
+
|
| 361 |
+
We experimented with larger models like [`gpt-oss-20b`](https://huggingface.co/openai/gpt-oss-20b) and found that it was able to consistently win the game, though this requires significantly more compute.
|
| 362 |
+
|
| 363 |
+
## Multi-environment training
|
| 364 |
+
|
| 365 |
+
You can train a single model across multiple environments simultaneously. This is useful when you want a model to learn different skills in parallel. For example, playing Wordle (language reasoning) and Catch (spatial reasoning) in the same training run.
|
| 366 |
+
|
| 367 |
+
The key idea is to create a **meta-environment class** that wraps multiple environments and routes each sample to the correct one using a dataset column.
|
| 368 |
+
|
| 369 |
+
### How it works
|
| 370 |
+
|
| 371 |
+
1. Add an `"env"` column (or similar) to your dataset that identifies which environment each sample belongs to.
|
| 372 |
+
2. In `reset(**kwargs)`, read `kwargs["env"]` to select the active environment for that episode.
|
| 373 |
+
3. Expose tools from all environments; the trainer discovers all public methods.
|
| 374 |
+
4. Use separate reward functions per environment, returning `None` for samples that don't belong to that environment. TRL handles `None` values with `nansum`/`nanmean`.
|
| 375 |
+
|
| 376 |
+
### Example: Wordle + Catch
|
| 377 |
+
|
| 378 |
+
The [multi_env.py](https://github.com/huggingface/trl/blob/main/examples/scripts/openenv/multi_env.py) script trains on Wordle and Catch simultaneously:
|
| 379 |
+
|
| 380 |
+
```python
|
| 381 |
+
class MultiEnv:
|
| 382 |
+
def __init__(self):
|
| 383 |
+
self._wordle_client = None
|
| 384 |
+
self._catch_client = None
|
| 385 |
+
self.active = None
|
| 386 |
+
self.reward = 0.0
|
| 387 |
+
self.done = False
|
| 388 |
+
|
| 389 |
+
def reset(self, **kwargs) -> str | None:
|
| 390 |
+
self.active = kwargs.get("env", "wordle")
|
| 391 |
+
self.reward = 0.0
|
| 392 |
+
self.done = False
|
| 393 |
+
|
| 394 |
+
if self.active == "wordle":
|
| 395 |
+
if self._wordle_client is not None:
|
| 396 |
+
try:
|
| 397 |
+
self._wordle_client.close()
|
| 398 |
+
except Exception:
|
| 399 |
+
pass
|
| 400 |
+
self._wordle_client = TextArenaEnv(base_url=WORDLE_URL)
|
| 401 |
+
result = self._wordle_client.reset()
|
| 402 |
+
self._last_full_feedback = result.observation.messages[0].content
|
| 403 |
+
self.reward = 0.0
|
| 404 |
+
return self._last_full_feedback
|
| 405 |
+
elif self.active == "catch":
|
| 406 |
+
if self._catch_client is not None:
|
| 407 |
+
try:
|
| 408 |
+
self._catch_client.close()
|
| 409 |
+
except Exception:
|
| 410 |
+
pass
|
| 411 |
+
self._catch_client = OpenSpielEnv(base_url=CATCH_URL)
|
| 412 |
+
result = self._catch_client.reset()
|
| 413 |
+
self.done = result.observation.done
|
| 414 |
+
return _format_catch_obs(result.observation.info_state)
|
| 415 |
+
|
| 416 |
+
# Wordle tool
|
| 417 |
+
def guess(self, guess: str) -> str:
|
| 418 |
+
"""Make a guess in the Wordle environment. ..."""
|
| 419 |
+
...
|
| 420 |
+
|
| 421 |
+
# Catch tools
|
| 422 |
+
def move(self, direction: str) -> str:
|
| 423 |
+
"""Move the paddle left or right. ..."""
|
| 424 |
+
...
|
| 425 |
+
|
| 426 |
+
def stay(self) -> str:
|
| 427 |
+
"""Do nothing and let the ball fall one step. ..."""
|
| 428 |
+
...
|
| 429 |
+
```
|
| 430 |
+
|
| 431 |
+
Key patterns:
|
| 432 |
+
|
| 433 |
+
- **Lazy client initialization**: Create clients in `reset()`, not `__init__()`, to avoid unnecessary WebSocket connections.
|
| 434 |
+
- **Close before reopen**: Close the previous client before creating a new one to avoid server capacity errors.
|
| 435 |
+
- **`kwargs` routing**: The `"env"` column from the dataset is passed to `reset()` as a keyword argument.
|
| 436 |
+
- **All tools are exposed simultaneously**: The model sees `guess`, `move`, and `stay` as available tools regardless of the active environment. If it calls the wrong tool (e.g., `move` during Wordle), the method raises a `ValueError` that the trainer catches gracefully. In practice, models learn to use the correct tools based on the system prompt.
|
| 437 |
+
|
| 438 |
+
### Per-environment reward functions
|
| 439 |
+
|
| 440 |
+
Each reward function returns `None` for samples from other environments:
|
| 441 |
+
|
| 442 |
+
```python
|
| 443 |
+
def wordle_reward(environments, **kwargs) -> list[float | None]:
|
| 444 |
+
return [env.reward if env.active == "wordle" else None for env in environments]
|
| 445 |
+
|
| 446 |
+
def catch_reward(environments, **kwargs) -> list[float | None]:
|
| 447 |
+
rewards = []
|
| 448 |
+
for env in environments:
|
| 449 |
+
if env.active != "catch":
|
| 450 |
+
rewards.append(None)
|
| 451 |
+
elif env.done:
|
| 452 |
+
rewards.append(max(env.reward, 0.0))
|
| 453 |
+
else:
|
| 454 |
+
rewards.append(0.0)
|
| 455 |
+
return rewards
|
| 456 |
+
```
|
| 457 |
+
|
| 458 |
+
TRL converts `None` to `nan` internally and uses `nansum`/`nanmean` for aggregation, so each sample is only scored by its relevant reward function.
|
| 459 |
+
|
| 460 |
+
### Dataset with environment routing
|
| 461 |
+
|
| 462 |
+
```python
|
| 463 |
+
n = 500
|
| 464 |
+
dataset = Dataset.from_dict({
|
| 465 |
+
"prompt": (
|
| 466 |
+
[[{"role": "user", "content": wordle_prompt}]] * n
|
| 467 |
+
+ [[{"role": "user", "content": catch_prompt}]] * n
|
| 468 |
+
),
|
| 469 |
+
"env": ["wordle"] * n + ["catch"] * n,
|
| 470 |
+
})
|
| 471 |
+
```
|
| 472 |
+
|
| 473 |
+
### Running the multi-environment example
|
| 474 |
+
|
| 475 |
+
```bash
|
| 476 |
+
python examples/scripts/openenv/multi_env.py \
|
| 477 |
+
--wordle-url https://openenv-wordle.hf.space \
|
| 478 |
+
--catch-url https://openenv-openspiel-env.hf.space \
|
| 479 |
+
--vllm-mode colocate \
|
| 480 |
+
--gradient-accumulation-steps 4 \
|
| 481 |
+
--num-generations 8
|
| 482 |
+
```
|
| 483 |
+
|
| 484 |
+
> [!TIP]
|
| 485 |
+
> When training across multiple environments, monitor the per-reward-function metrics (`train/reward_func_0`, `train/reward_func_1`, etc.) rather than the combined `train/reward`. The combined metric alternates between environments and can appear noisy.
|
| 486 |
+
|
| 487 |
+
## Running the environments
|
| 488 |
+
|
| 489 |
+
When using `environment_factory`, the trainer connects to the environment server automatically. You just need the server to be running. There are three ways to run an OpenEnv environment server:
|
| 490 |
+
|
| 491 |
+
<hfoptions id="env_mode">
|
| 492 |
+
|
| 493 |
+
<hfoption id="space">
|
| 494 |
+
|
| 495 |
+
**Connect to a remote Hugging Face Space** *(simplest)*
|
| 496 |
+
|
| 497 |
+
Most example scripts default to a hosted Space (no setup needed):
|
| 498 |
+
|
| 499 |
+
```python
|
| 500 |
+
env = EchoEnv(base_url="https://openenv-echo-env.hf.space")
|
| 501 |
+
```
|
| 502 |
+
|
| 503 |
+
> [!WARNING]
|
| 504 |
+
> For training, **duplicate the Space to your own account** to avoid concurrency issues. The trainer opens N simultaneous WebSocket connections (one per generation), and shared Spaces may not support this. See [Server concurrency](#server-concurrency) for details.
|
| 505 |
+
|
| 506 |
+
</hfoption>
|
| 507 |
+
|
| 508 |
+
<hfoption id="docker">
|
| 509 |
+
|
| 510 |
+
**Docker container** *(recommended for production)*
|
| 511 |
+
|
| 512 |
+
```bash
|
| 513 |
+
docker run -d -p 8001:8000 --platform linux/amd64 registry.hf.space/openenv-echo-env:latest
|
| 514 |
+
```
|
| 515 |
+
|
| 516 |
+
Then connect:
|
| 517 |
+
|
| 518 |
+
```python
|
| 519 |
+
env = EchoEnv(base_url="http://0.0.0.0:8001")
|
| 520 |
+
```
|
| 521 |
+
|
| 522 |
+
We map port 8001 to 8000 to leave port 8000 available for a vLLM server.
|
| 523 |
+
|
| 524 |
+
You can also start the container programmatically:
|
| 525 |
+
|
| 526 |
+
```python
|
| 527 |
+
env = EchoEnv.from_docker_image("registry.hf.space/openenv-echo-env:latest")
|
| 528 |
+
```
|
| 529 |
+
|
| 530 |
+
> [!NOTE]
|
| 531 |
+
> You can find the Docker image for any Space on the Hub: open the Space page → **⋮ (three dots)** → **"Run locally."**
|
| 532 |
+
>
|
| 533 |
+
> 
|
| 534 |
+
|
| 535 |
+
</hfoption>
|
| 536 |
+
|
| 537 |
+
<hfoption id="local">
|
| 538 |
+
|
| 539 |
+
**Local Python process** *(for development)*
|
| 540 |
+
|
| 541 |
+
```bash
|
| 542 |
+
hf download openenv/echo_env --repo-type=space --local-dir=echo_env
|
| 543 |
+
python -m uvicorn echo_env.src.envs.echo_env.server.app:app --host 0.0.0.0 --port 8001
|
| 544 |
+
```
|
| 545 |
+
|
| 546 |
+
Then connect:
|
| 547 |
+
|
| 548 |
+
```python
|
| 549 |
+
env = EchoEnv(base_url="http://0.0.0.0:8001")
|
| 550 |
+
```
|
| 551 |
+
|
| 552 |
+
For more details, see the [OpenEnv catalog](https://meta-pytorch.org/OpenEnv/environments.html).
|
| 553 |
+
|
| 554 |
+
</hfoption>
|
| 555 |
+
|
| 556 |
+
</hfoptions>
|
| 557 |
+
|
| 558 |
+
## Environments catalog
|
| 559 |
+
|
| 560 |
+
The best way to explore the current catalog of maintained environments is by visiting the official OpenEnv [catalog](https://huggingface.co/collections/openenv/environment-hub).
|
| 561 |
+
|
| 562 |
+
To create your own environment, check out the guide on [Building Your Own Environment with OpenEnv](https://meta-pytorch.org/OpenEnv/auto_getting_started/plot_03_building_environments.html). Environments are tightly integrated with the Hub, so you can push new environments for the community to reuse.
|
| 563 |
+
|
| 564 |
+
## Server concurrency
|
| 565 |
+
|
| 566 |
+
When using `environment_factory`, the trainer creates N environment instances (one per generation), each opening a WebSocket connection to the server. By default, OpenEnv servers allow only 1 concurrent session, which will cause failures during training.
|
| 567 |
+
|
| 568 |
+
To support parallel training, configure the server for concurrency:
|
| 569 |
+
|
| 570 |
+
1. In your environment file, declare concurrent session support:
|
| 571 |
+
```python
|
| 572 |
+
SUPPORTS_CONCURRENT_SESSIONS: bool = True
|
| 573 |
+
```
|
| 574 |
+
|
| 575 |
+
2. In your server app, set the concurrency limit:
|
| 576 |
+
```python
|
| 577 |
+
app = create_app(
|
| 578 |
+
create_my_environment,
|
| 579 |
+
MyAction,
|
| 580 |
+
MyObservation,
|
| 581 |
+
max_concurrent_envs=64, # match or exceed generation_batch_size
|
| 582 |
+
)
|
| 583 |
+
```
|
| 584 |
+
|
| 585 |
+
> [!TIP]
|
| 586 |
+
> `max_concurrent_envs` should be ≥ `generation_batch_size` (which defaults to `per_device_train_batch_size × gradient_accumulation_steps`). For example, with `gradient_accumulation_steps=64` and batch size 1, you need at least 64 concurrent sessions.
|
| 587 |
+
|
| 588 |
+
## `environment_factory` vs `rollout_func`
|
| 589 |
+
|
| 590 |
+
[`GRPOTrainer`] supports two approaches for environment-based training:
|
| 591 |
+
|
| 592 |
+
- **`environment_factory`** (recommended): You define an environment class with tool methods, and the trainer handles generation, tool-call parsing, and the multi-turn loop automatically. This is the approach used throughout this guide.
|
| 593 |
+
- **`rollout_func`**: You write the entire generation and environment interaction loop yourself. This gives full control over how completions are produced, how tools are executed, and how rewards are computed.
|
| 594 |
+
|
| 595 |
+
Use `rollout_func` when `environment_factory` doesn't fit your use case. For example, **external agent servers** like [NeMo-Gym](nemo_gym), where an external server owns the generation loop and manages its own agent-environment interaction protocol.
|
| 596 |
+
|
| 597 |
+
### Migrating from `rollout_func` to `environment_factory`
|
| 598 |
+
|
| 599 |
+
If you have existing `rollout_func` code and want to migrate, here's the mapping:
|
| 600 |
+
|
| 601 |
+
| `rollout_func` pattern | `environment_factory` equivalent |
|
| 602 |
+
|------------------------|----------------------------------|
|
| 603 |
+
| Manual generation loop | Handled automatically by the trainer |
|
| 604 |
+
| `generate_rollout_completions()` | Not needed, trainer generates internally |
|
| 605 |
+
| `env.step(Action(...))` in rollout | Wrap in a tool method on the environment class |
|
| 606 |
+
| Reward via `kwargs["env_reward"]` | Reward via `environments` parameter |
|
| 607 |
+
| `env_mask` construction | Automatic, trainer builds `tool_mask` |
|
| 608 |
+
| Token concatenation | Automatic, trainer manages token sequences |
|
| 609 |
+
|
| 610 |
+
**Before** (`rollout_func`):
|
| 611 |
+
|
| 612 |
+
```python
|
| 613 |
+
def rollout_func(prompts, trainer):
|
| 614 |
+
outputs = generate_rollout_completions(trainer, prompts)
|
| 615 |
+
env_rewards = []
|
| 616 |
+
for out in outputs:
|
| 617 |
+
text = tokenizer.decode(out["completion_ids"], skip_special_tokens=True)
|
| 618 |
+
result = client.step(EchoAction(message=text))
|
| 619 |
+
env_rewards.append(result.reward)
|
| 620 |
+
return {
|
| 621 |
+
"prompt_ids": [out["prompt_ids"] for out in outputs],
|
| 622 |
+
"completion_ids": [out["completion_ids"] for out in outputs],
|
| 623 |
+
"logprobs": [out["logprobs"] for out in outputs],
|
| 624 |
+
"env_reward": env_rewards,
|
| 625 |
+
}
|
| 626 |
+
|
| 627 |
+
trainer = GRPOTrainer(..., rollout_func=rollout_func)
|
| 628 |
+
```
|
| 629 |
+
|
| 630 |
+
**After** (`environment_factory`):
|
| 631 |
+
|
| 632 |
+
```python
|
| 633 |
+
class EchoToolEnv:
|
| 634 |
+
def __init__(self):
|
| 635 |
+
self.env = EchoEnv(base_url=url)
|
| 636 |
+
self.reward = 0.0
|
| 637 |
+
|
| 638 |
+
def reset(self, **kwargs) -> str | None:
|
| 639 |
+
self.reward = 0.0
|
| 640 |
+
return None
|
| 641 |
+
|
| 642 |
+
def echo(self, message: str) -> str:
|
| 643 |
+
"""Echo the message back.
|
| 644 |
+
|
| 645 |
+
Args:
|
| 646 |
+
message: The message to echo
|
| 647 |
+
|
| 648 |
+
Returns:
|
| 649 |
+
The echoed message.
|
| 650 |
+
"""
|
| 651 |
+
result = self.env.step(EchoAction(message=message))
|
| 652 |
+
self.reward = result.observation.reward
|
| 653 |
+
return result.observation.echoed_message
|
| 654 |
+
|
| 655 |
+
def reward_func(environments, **kwargs):
|
| 656 |
+
return [env.reward for env in environments]
|
| 657 |
+
|
| 658 |
+
trainer = GRPOTrainer(..., environment_factory=EchoToolEnv, reward_funcs=reward_func)
|
| 659 |
+
```
|
tasks/tasksmith-1c108f674e97/tests/source/docs/source/orpo_trainer.md
ADDED
|
@@ -0,0 +1,131 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# ORPO Trainer
|
| 2 |
+
|
| 3 |
+
[](https://huggingface.co/models?other=orpo,trl) [](https://github.com/huggingface/smol-course/tree/main/2_preference_alignment)
|
| 4 |
+
|
| 5 |
+
## Overview
|
| 6 |
+
|
| 7 |
+
Odds Ratio Preference Optimization (ORPO) was introduced in [ORPO: Monolithic Preference Optimization without Reference Model](https://huggingface.co/papers/2403.07691) by [Jiwoo Hong](https://huggingface.co/JW17), [Noah Lee](https://huggingface.co/nlee-208), and [James Thorne](https://huggingface.co/j6mes).
|
| 8 |
+
|
| 9 |
+
The abstract from the paper is the following:
|
| 10 |
+
|
| 11 |
+
> While recent preference alignment algorithms for language models have demonstrated promising results, supervised fine-tuning (SFT) remains imperative for achieving successful convergence. In this paper, we study the crucial role of SFT within the context of preference alignment, emphasizing that a minor penalty for the disfavored generation style is sufficient for preference-aligned SFT. Building on this foundation, we introduce a straightforward and innovative reference model-free monolithic odds ratio preference optimization algorithm, ORPO, eliminating the necessity for an additional preference alignment phase. We demonstrate, both empirically and theoretically, that the odds ratio is a sensible choice for contrasting favored and disfavored styles during SFT across the diverse sizes from 125M to 7B. Specifically, fine-tuning Phi-2 (2.7B), Llama-2 (7B), and Mistral (7B) with ORPO on the UltraFeedback alone surpasses the performance of state-of-the-art language models with more than 7B and 13B parameters: achieving up to 12.20% on AlpacaEval_{2.0} (Figure 1), 66.19% on IFEval (instruction-level loose, Table 6), and 7.32 in MT-Bench (Figure 12). We release code and model checkpoints for Mistral-ORPO-alpha (7B) and Mistral-ORPO-beta (7B).
|
| 12 |
+
|
| 13 |
+
It studies the crucial role of SFT within the context of preference alignment. Using preference data the method posits that a minor penalty for the disfavored generation together with a strong adaption signal to the chosen response via a simple log odds ratio term appended to the NLL loss is sufficient for preference-aligned SFT.
|
| 14 |
+
|
| 15 |
+
Thus ORPO is a reference model-free preference optimization algorithm eliminating the necessity for an additional preference alignment phase thus saving compute and memory.
|
| 16 |
+
|
| 17 |
+
The official code can be found in [xfactlab/orpo](https://github.com/xfactlab/orpo).
|
| 18 |
+
|
| 19 |
+
This post-training method was contributed by [Kashif Rasul](https://huggingface.co/kashif), [Lewis Tunstall](https://huggingface.co/lewtun) and [Alvaro Bartolome](https://huggingface.co/alvarobartt).
|
| 20 |
+
|
| 21 |
+
## Quick start
|
| 22 |
+
|
| 23 |
+
This example demonstrates how to train a model using the ORPO method. We use the [Qwen 0.5B model](https://huggingface.co/Qwen/Qwen2-0.5B-Instruct) as the base model. We use the preference data from the [UltraFeedback dataset](https://huggingface.co/datasets/openbmb/UltraFeedback). You can view the data in the dataset here:
|
| 24 |
+
|
| 25 |
+
<iframe
|
| 26 |
+
src="https://huggingface.co/datasets/trl-lib/ultrafeedback_binarized/embed/viewer/default/train?row=0"
|
| 27 |
+
frameborder="0"
|
| 28 |
+
width="100%"
|
| 29 |
+
height="560px"
|
| 30 |
+
></iframe>
|
| 31 |
+
|
| 32 |
+
Below is the script to train the model:
|
| 33 |
+
|
| 34 |
+
```python
|
| 35 |
+
# train_orpo.py
|
| 36 |
+
from datasets import load_dataset
|
| 37 |
+
from trl.experimental.orpo import ORPOConfig, ORPOTrainer
|
| 38 |
+
from transformers import AutoModelForCausalLM, AutoTokenizer
|
| 39 |
+
|
| 40 |
+
model = AutoModelForCausalLM.from_pretrained("Qwen/Qwen2-0.5B-Instruct")
|
| 41 |
+
tokenizer = AutoTokenizer.from_pretrained("Qwen/Qwen2-0.5B-Instruct")
|
| 42 |
+
train_dataset = load_dataset("trl-lib/ultrafeedback_binarized", split="train")
|
| 43 |
+
|
| 44 |
+
training_args = ORPOConfig(output_dir="Qwen2-0.5B-ORPO")
|
| 45 |
+
trainer = ORPOTrainer(model=model, args=training_args, processing_class=tokenizer, train_dataset=train_dataset)
|
| 46 |
+
trainer.train()
|
| 47 |
+
```
|
| 48 |
+
|
| 49 |
+
Execute the script using the following command:
|
| 50 |
+
|
| 51 |
+
```bash
|
| 52 |
+
accelerate launch train_orpo.py
|
| 53 |
+
```
|
| 54 |
+
|
| 55 |
+
Distributed across 8 GPUs, the training takes approximately 30 minutes. You can verify the training progress by checking the reward graph. An increasing trend in the reward margin indicates that the model is improving and generating better responses over time.
|
| 56 |
+
|
| 57 |
+

|
| 58 |
+
|
| 59 |
+
To see how the [trained model](https://huggingface.co/trl-lib/Qwen2-0.5B-ORPO) performs, you can use the [Transformers Chat CLI](https://huggingface.co/docs/transformers/quicktour#chat-with-text-generation-models).
|
| 60 |
+
|
| 61 |
+
<pre><code>$ transformers chat trl-lib/Qwen2-0.5B-ORPO
|
| 62 |
+
<strong><span style="color: red;"><quentin_gallouedec>:</span></strong>
|
| 63 |
+
What is the best programming language?
|
| 64 |
+
|
| 65 |
+
<strong><span style="color: blue;"><trl-lib/Qwen2-0.5B-ORPO>:</span></strong>
|
| 66 |
+
It's challenging to determine the best programming language as no one language is perfect, as the complexity of a task and the type of project are significant factors. Some popular languages include Java, Python, JavaScript, and
|
| 67 |
+
C++. If you have specific needs or requirements for a specific project, it's important to choose the language that best suits those needs.
|
| 68 |
+
|
| 69 |
+
Here are some other factors to consider when choosing a programming language for a project:
|
| 70 |
+
|
| 71 |
+
<strong><span style="color: green;">• Language proficiency:</span></strong> A good programming language is more likely to be easy to understand and use, and will allow developers to collaborate on projects more efficiently.
|
| 72 |
+
<strong><span style="color: green;">• Ease of use:</span></strong> There are tools and libraries available to make programming more accessible, so developers should choose a language that can help them get started easier.
|
| 73 |
+
<strong><span style="color: green;">• Code readability:</span></strong> A clear and concise codebase should be easy to read and understand, especially when working with large projects.
|
| 74 |
+
<strong><span style="color: green;">• Tool and framework support:</span></strong> There are numerous libraries available for Python, Java, and JavaScript, along with tools like IDEs and static code analysis tools.
|
| 75 |
+
<strong><span style="color: green;">• Accessibility:</span></strong> Some languages and tools have features that make them more accessible to developers with disabilities, such as support for screen readers.
|
| 76 |
+
<strong><span style="color: green;">• Version control:</span></strong> As your projects grow and complexity increases, version control tools can be beneficial for tracking changes.
|
| 77 |
+
|
| 78 |
+
</code></pre>
|
| 79 |
+
|
| 80 |
+
## Expected dataset type
|
| 81 |
+
|
| 82 |
+
ORPO requires a [preference dataset](dataset_formats#preference). The [`experimental.orpo.ORPOTrainer`] supports both [conversational](dataset_formats#conversational) and [standard](dataset_formats#standard) dataset format. When provided with a conversational dataset, the trainer will automatically apply the chat template to the dataset.
|
| 83 |
+
|
| 84 |
+
Although the [`experimental.orpo.ORPOTrainer`] supports both explicit and implicit prompts, we recommend using explicit prompts. If provided with an implicit prompt dataset, the trainer will automatically extract the prompt from the `"chosen"` and `"rejected"` columns. For more information, refer to the [preference style](dataset_formats#preference) section.
|
| 85 |
+
|
| 86 |
+
## Example script
|
| 87 |
+
|
| 88 |
+
We provide an example script to train a model using the ORPO method. The script is available in [`examples/scripts/orpo.py`](https://github.com/huggingface/trl/blob/main/examples/scripts/orpo.py)
|
| 89 |
+
|
| 90 |
+
To test the ORPO script with the [Qwen2 0.5B model](https://huggingface.co/Qwen/Qwen2-0.5B-Instruct) on the [UltraFeedback dataset](https://huggingface.co/datasets/trl-lib/ultrafeedback_binarized), run the following command:
|
| 91 |
+
|
| 92 |
+
```bash
|
| 93 |
+
accelerate launch examples/scripts/orpo.py \
|
| 94 |
+
--model_name_or_path Qwen/Qwen2-0.5B-Instruct \
|
| 95 |
+
--dataset_name trl-lib/ultrafeedback_binarized \
|
| 96 |
+
--num_train_epochs 1 \
|
| 97 |
+
--output_dir Qwen2-0.5B-ORPO
|
| 98 |
+
```
|
| 99 |
+
|
| 100 |
+
## Usage tips
|
| 101 |
+
|
| 102 |
+
### For Mixture of Experts Models: Enabling the auxiliary loss
|
| 103 |
+
|
| 104 |
+
MOEs are the most efficient if the load is about equally distributed between experts.
|
| 105 |
+
To ensure that we train MOEs similarly during preference-tuning, it is beneficial to add the auxiliary loss from the load balancer to the final loss.
|
| 106 |
+
|
| 107 |
+
This option is enabled by setting `output_router_logits=True` in the model config (e.g. [`~transformers.MixtralConfig`]).
|
| 108 |
+
To scale how much the auxiliary loss contributes to the total loss, use the hyperparameter `router_aux_loss_coef=...` (default: `0.001`) in the model config.
|
| 109 |
+
|
| 110 |
+
## Logged metrics
|
| 111 |
+
|
| 112 |
+
While training and evaluating, we record the following reward metrics:
|
| 113 |
+
|
| 114 |
+
- `rewards/chosen`: the mean log probabilities of the policy model for the chosen responses scaled by beta
|
| 115 |
+
- `rewards/rejected`: the mean log probabilities of the policy model for the rejected responses scaled by beta
|
| 116 |
+
- `rewards/accuracies`: mean of how often the chosen rewards are > than the corresponding rejected rewards
|
| 117 |
+
- `rewards/margins`: the mean difference between the chosen and corresponding rejected rewards
|
| 118 |
+
- `log_odds_chosen`: the mean log odds ratio of the chosen responses over the rejected responses
|
| 119 |
+
- `log_odds_ratio`: the mean of the `log(sigmoid(log_odds_chosen))`
|
| 120 |
+
- `nll_loss`: the mean negative log likelihood loss from the SFT part of the loss over chosen responses
|
| 121 |
+
|
| 122 |
+
## ORPOTrainer
|
| 123 |
+
|
| 124 |
+
[[autodoc]] experimental.orpo.ORPOTrainer
|
| 125 |
+
- train
|
| 126 |
+
- save_model
|
| 127 |
+
- push_to_hub
|
| 128 |
+
|
| 129 |
+
## ORPOConfig
|
| 130 |
+
|
| 131 |
+
[[autodoc]] experimental.orpo.ORPOConfig
|
tasks/tasksmith-1c108f674e97/tests/source/docs/source/paper_index.md
ADDED
|
@@ -0,0 +1,1825 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Paper Index
|
| 2 |
+
|
| 3 |
+
<!-- Within sections, papers are sorted by publish dates -->
|
| 4 |
+
|
| 5 |
+
## Group Relative Policy Optimization
|
| 6 |
+
|
| 7 |
+
Papers relating to the [`GRPOTrainer`].
|
| 8 |
+
|
| 9 |
+
### DeepSeekMath: Pushing the Limits of Mathematical Reasoning in Open Language Models
|
| 10 |
+
|
| 11 |
+
**📜 Paper**: https://huggingface.co/papers/2402.03300
|
| 12 |
+
|
| 13 |
+
Introduces Group Relative Policy Optimization (GRPO) and shows strong math-reasoning gains from math-centric pretraining plus group-relative PPO-style optimization. Used in TRL via [`GRPOTrainer`].
|
| 14 |
+
|
| 15 |
+
```python
|
| 16 |
+
from trl import GRPOConfig, GRPOTrainer
|
| 17 |
+
|
| 18 |
+
# The paper doesn't specify its hyperparameters, so here we provide hyperparameters from "DeepSeek-R1 incentivizes reasoning in LLMs through reinforcement learning" instead.
|
| 19 |
+
training_args = GRPOConfig(
|
| 20 |
+
loss_type="grpo",
|
| 21 |
+
beta=0.001, # "the KL coefficient to 0.001"
|
| 22 |
+
epsilon=10.0, # "the GRPO clip ratio ϵ to 10"
|
| 23 |
+
num_generations=16, # "For each question, we sample 16 outputs..."
|
| 24 |
+
max_completion_length=32_768, # "...with a maximum length of 32,768"
|
| 25 |
+
steps_per_generation=16, # "To accelerate training, each rollout generates 8,192 outputs, which are randomly split into 16 minibatches"
|
| 26 |
+
# "resulting in a training batch size of 512". One way to achieve this setting with 1 device is per_device_train_batch_size=4, gradient_accumulation_steps=128
|
| 27 |
+
per_device_train_batch_size=4,
|
| 28 |
+
gradient_accumulation_steps=128,
|
| 29 |
+
)
|
| 30 |
+
trainer = GRPOTrainer(
|
| 31 |
+
...,
|
| 32 |
+
args=training_args,
|
| 33 |
+
)
|
| 34 |
+
```
|
| 35 |
+
|
| 36 |
+
### DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning
|
| 37 |
+
|
| 38 |
+
**📜 Paper**: https://huggingface.co/papers/2501.12948
|
| 39 |
+
|
| 40 |
+
DeepSeek-R1 achieves reasoning performance comparable to OpenAI-o1 through a multi-stage pipeline that transitions from pure reinforcement learning (RL) to a refined, human-aligned model. Unlike its predecessor, DeepSeek-R1-Zero, which used pure RL on a base model, R1 follows a structured four-stage evolution:
|
| 41 |
+
1. Cold Start: The base model is fine-tuned on a small set of high-quality, long Chain-of-Thought (CoT) data to provide a stable starting point.
|
| 42 |
+
2. Reasoning-Oriented RL: Large-scale RL is applied to enhance performance in math, coding, and logic, using rule-based rewards and a language consistency reward to reduce language mixing.
|
| 43 |
+
3. Rejection Sampling & SFT: The RL checkpoint generates 600k reasoning samples via rejection sampling, which are combined with 200k non-reasoning (general) samples to create a new dataset for a second round of Supervised Fine-Tuning.
|
| 44 |
+
4. RL for all Scenarios: A final RL stage aligns the model with human preferences (helpfulness and harmlessness) across all domains while maintaining reasoning strength.
|
| 45 |
+
|
| 46 |
+
Distillation: Empowering Small Models
|
| 47 |
+
|
| 48 |
+
A key contribution of the paper is demonstrating that reasoning patterns can be distilled from a large model (DeepSeek-R1) into smaller dense models (e.g., Qwen and Llama series). Distillation was found to be more effective for small models than training them with pure RL from scratch.
|
| 49 |
+
|
| 50 |
+
|
| 51 |
+
You can use the GRPOTrainer to replicate the reasoning-heavy stages of this pipeline.
|
| 52 |
+
```python
|
| 53 |
+
from trl import GRPOConfig, GRPOTrainer
|
| 54 |
+
|
| 55 |
+
# Example configuration for a reasoning-oriented GRPO stage
|
| 56 |
+
# Based on the Open-R1 recipe for Qwen-7B
|
| 57 |
+
training_args = GRPOConfig(
|
| 58 |
+
learning_rate=4.0e-5,
|
| 59 |
+
max_prompt_length=4096,
|
| 60 |
+
max_completion_length=32768, # Support for long Chain-of-Thought
|
| 61 |
+
num_generations=16, # Sample 16 outputs per prompt for group relative advantage
|
| 62 |
+
beta=0.001, # KL coefficient
|
| 63 |
+
use_vllm=True, # Use vLLM backend for accelerated rollout generation
|
| 64 |
+
)
|
| 65 |
+
|
| 66 |
+
trainer = GRPOTrainer(
|
| 67 |
+
model=model,
|
| 68 |
+
args=training_args,
|
| 69 |
+
train_dataset=dataset,
|
| 70 |
+
reward_funcs=[accuracy_reward, format_reward], # R1-Zero used rule-based rewards
|
| 71 |
+
)
|
| 72 |
+
|
| 73 |
+
trainer.train()
|
| 74 |
+
```
|
| 75 |
+
|
| 76 |
+
|
| 77 |
+
### Group Sequence Policy Optimization
|
| 78 |
+
|
| 79 |
+
**📜 Paper**: https://huggingface.co/papers/2507.18071
|
| 80 |
+
|
| 81 |
+
GSPO is a GRPO variant that computes importance sampling weights at the sequence level instead of per-token. To reproduce the paper's setting, use this configuration:
|
| 82 |
+
|
| 83 |
+
```python
|
| 84 |
+
from trl import GRPOConfig
|
| 85 |
+
|
| 86 |
+
training_args = GRPOConfig(
|
| 87 |
+
importance_sampling_level="sequence",
|
| 88 |
+
loss_type="grpo",
|
| 89 |
+
beta=0.0, # GSPO set KL regularization to zero: https://github.com/volcengine/verl/pull/2775#issuecomment-3131807306
|
| 90 |
+
epsilon=3e-4, # GSPO paper (v2), section 5.1
|
| 91 |
+
epsilon_high=4e-4, # GSPO paper (v2), section 5.1
|
| 92 |
+
gradient_accumulation_steps=1,
|
| 93 |
+
steps_per_generation=4, # partition rollout batch into 4 mini-batches. GSPO paper (v2), section 5.1. Must be 4 times gradient_accumulation_steps
|
| 94 |
+
)
|
| 95 |
+
```
|
| 96 |
+
|
| 97 |
+
Note that this method only has an effect when training goes slightly off-policy—for example, when `steps_per_generation > gradient_accumulation_steps` or `num_iterations > 1`. Otherwise, it is effectively equivalent to no modification.
|
| 98 |
+
|
| 99 |
+
TRL also provide an experimental implementation of GSPO-token, see [Experimental - GSPO-Token](experimental#gspo-token).
|
| 100 |
+
|
| 101 |
+
#### Policy ratio: GRPO vs. GSPO
|
| 102 |
+
|
| 103 |
+
In GSPO, the policy ratio is defined at the sequence-level. In other words, it is the ratio between the probability of the current policy generating a sequence over the old policy generating that same sequence.
|
| 104 |
+
|
| 105 |
+
The sequence likelihood is defined as:
|
| 106 |
+
|
| 107 |
+
$$
|
| 108 |
+
\pi_\theta (o_i | q) = \prod_{t=1}^{|o_i|} \pi_\theta (o_{i,t} | q, o_{i, < t} ),
|
| 109 |
+
$$
|
| 110 |
+
|
| 111 |
+
where \\( \pi_\theta \\) is the policy \\( \pi \\) with parameters \\(\theta\\), \\( o_i \\) is the \\( i \\)-th output sequence \\( o \\) and \\(o_{i,t}\\) is the \\( t \\)-th token in this sequence, \\( q \\) is the input query. The sequence likelihood ratio \\( s_i (\theta) \\) is defined as:
|
| 112 |
+
|
| 113 |
+
$$
|
| 114 |
+
s_i (\theta) = \left(\frac{\pi_\theta (o_i | q)}{\pi_{\theta_{old}} (o_i | q)} \right)^{\frac{1}{|o_i|}}
|
| 115 |
+
$$
|
| 116 |
+
|
| 117 |
+
The exponent \\( \frac{1}{|o_i|} \\) represents a sequence-length normalization, minimizing the influence of sequence length in sequence likelihood. In other terms, it computes the geometric mean of token probabilities, ensuring a fair comparison across sequences of varying lengths.
|
| 118 |
+
|
| 119 |
+
While GSPO defines the policy ratio at the sequence level, GRPO operates at the token level. Specifically, GRPO computes an importance ratio for each token in the sequence:
|
| 120 |
+
|
| 121 |
+
$$
|
| 122 |
+
w_{i,t}(\theta) = \frac{\pi_\theta (o_{i,t} | q, o_{i,< t})}{\pi_{\theta_{\text{old}}} (o_{i,t} | q, o_{i,< t})}
|
| 123 |
+
$$
|
| 124 |
+
|
| 125 |
+
This token-level ratio is then combined with a shared advantage \\( \hat{A}_i \\), and the GRPO objective clips and optimizes each token independently across the sequence.
|
| 126 |
+
|
| 127 |
+
### DAPO: An Open-Source LLM Reinforcement Learning System at Scale
|
| 128 |
+
|
| 129 |
+
**📜 Paper**: https://huggingface.co/papers/2503.14476
|
| 130 |
+
|
| 131 |
+
The DAPO algorithm includes 5 key components:
|
| 132 |
+
|
| 133 |
+
- Overlong Filtering
|
| 134 |
+
- Clip-Higher
|
| 135 |
+
- Soft Overlong Punishment
|
| 136 |
+
- Token-level Loss
|
| 137 |
+
- Dynamic Sampling (⚠️ Not supported in TRL)
|
| 138 |
+
|
| 139 |
+
To reproduce the paper's setting, use this configuration:
|
| 140 |
+
|
| 141 |
+
```python
|
| 142 |
+
from trl import GRPOConfig, GRPOTrainer
|
| 143 |
+
|
| 144 |
+
training_args = GRPOConfig(
|
| 145 |
+
# Overlong Filtering
|
| 146 |
+
mask_truncated_completions=True,
|
| 147 |
+
# Token-level Loss
|
| 148 |
+
loss_type="dapo",
|
| 149 |
+
# Clip-Higher
|
| 150 |
+
epsilon_high=0.28, # DAPO paper: section 4.1
|
| 151 |
+
epsilon=0.2, # DAPO paper: section 4.1
|
| 152 |
+
# Other parameters used
|
| 153 |
+
per_device_train_batch_size=512, # mini-batch size for training in the paper, DAPO paper: section 4.1
|
| 154 |
+
num_generations=16, # number of sample responses in the paper, DAPO paper: section 4.1
|
| 155 |
+
max_completion_length=20480, # maximum number of tokens for generation in the paper, DAPO paper: section 4.1
|
| 156 |
+
beta=0.0, # section 2.3, DAPO paper
|
| 157 |
+
|
| 158 |
+
)
|
| 159 |
+
# Soft Overlong Punishment
|
| 160 |
+
sop_reward = get_soft_overlong_punishment(max_completion_len=20480, soft_punish_cache=4096) # DAPO paper: section 4.1
|
| 161 |
+
trainer = GRPOTrainer(
|
| 162 |
+
...,
|
| 163 |
+
args=training_args,
|
| 164 |
+
reward_funcs=[..., sop_reward],
|
| 165 |
+
)
|
| 166 |
+
```
|
| 167 |
+
|
| 168 |
+
### INTELLECT-2: A Reasoning Model Trained Through Globally Decentralized Reinforcement Learning
|
| 169 |
+
|
| 170 |
+
**📜 Paper**: https://huggingface.co/papers/2505.07291
|
| 171 |
+
|
| 172 |
+
INTELLECT-2 is the first globally distributed reinforcement learning training run of a 32 billion parameter language model using fully asynchronous RL across a dynamic, heterogeneous swarm of permissionless compute contributors. The authors propose modifications to the standard GRPO training recipe, including two-sided GRPO clipping for increased training stability. To reproduce the paper's setting, use this configuration:
|
| 173 |
+
|
| 174 |
+
```python
|
| 175 |
+
from trl import GRPOConfig
|
| 176 |
+
|
| 177 |
+
training_args = GRPOConfig(
|
| 178 |
+
delta=4, # δ in section 4.1 of the paper
|
| 179 |
+
epsilon=0.2, # ε in section 4.1 of the paper
|
| 180 |
+
beta=0.001, # KL divergence coefficient in section 4.1 of the paper
|
| 181 |
+
num_generations=16, # responses per prompt in section 4.1 of the paper
|
| 182 |
+
learning_rate=3e-7, # section 4.1 of the paper
|
| 183 |
+
)
|
| 184 |
+
```
|
| 185 |
+
|
| 186 |
+
### Beyond the 80/20 Rule: High-Entropy Minority Tokens Drive Effective Reinforcement Learning for LLM Reasoning
|
| 187 |
+
|
| 188 |
+
**📜 Paper**: https://huggingface.co/papers/2506.01939
|
| 189 |
+
|
| 190 |
+
A minority of tokens with high entropy act as reasoning "forks" in the CoT path, driving exploration and performance gains for RLVR, while low-entropy majority tokens contribute little or even impede learning. RLVR mainly adjusts high-entropy tokens, largely preserving the base model’s overall entropy patterns. Thus landing on the 80/20 rule, training on only 20% of the tokens with the highest entropy is comparable or supasses full-gradient updates for Qwen3 models.
|
| 191 |
+
|
| 192 |
+
The paper's main results use vanilla DAPO (⚠️ Dynamic Sampling is not supported in TRL). To replicate the main results, use the following configuration:
|
| 193 |
+
|
| 194 |
+
```python
|
| 195 |
+
from trl import GRPOConfig, GRPOTrainer
|
| 196 |
+
from trl.rewards import get_soft_overlong_punishment
|
| 197 |
+
|
| 198 |
+
training_args = GRPOConfig(
|
| 199 |
+
# --- vanilla DAPO parameters (80/20 rule: section 5.2) --- #
|
| 200 |
+
# Overlong Filtering
|
| 201 |
+
mask_truncated_completions=True,
|
| 202 |
+
# Token-level Loss
|
| 203 |
+
loss_type="dapo",
|
| 204 |
+
# Clip-Higher
|
| 205 |
+
epsilon_high=0.28, # DAPO paper: section 4.1
|
| 206 |
+
epsilon=0.2, # DAPO paper: section 4.1
|
| 207 |
+
# Other parameters used
|
| 208 |
+
per_device_train_batch_size=512, # mini-batch size for training in the paper, DAPO paper: section 4.1
|
| 209 |
+
num_generations=16, # number of sample responses in the paper, DAPO paper: section 4.1
|
| 210 |
+
max_completion_length=20480, # maximum number of tokens for generation in the paper, DAPO paper: section 4.1
|
| 211 |
+
beta=0.0, # section 2.3, DAPO paper
|
| 212 |
+
# --- Gradients on the highest entropy tokens --- #
|
| 213 |
+
top_entropy_quantile=0.2
|
| 214 |
+
)
|
| 215 |
+
# Soft Overlong Punishment
|
| 216 |
+
sop_reward = get_soft_overlong_punishment(max_completion_len=20480, soft_punish_cache=4096) # DAPO paper: section 4.1
|
| 217 |
+
trainer = GRPOTrainer(
|
| 218 |
+
...,
|
| 219 |
+
args=training_args,
|
| 220 |
+
reward_funcs=[..., sop_reward],
|
| 221 |
+
)
|
| 222 |
+
```
|
| 223 |
+
|
| 224 |
+
### Dr. GRPO: Understanding R1-Zero-Like Training: A Critical Perspective
|
| 225 |
+
|
| 226 |
+
**📜 Paper**: https://huggingface.co/papers/2503.20783
|
| 227 |
+
|
| 228 |
+
A study of R1-Zero training identifies pretraining effects on RL performance and proffers Dr. GRPO to enhance token efficiency, achieving superior accuracy on AIME 2024. To reproduce the paper's setting, use this configuration:
|
| 229 |
+
|
| 230 |
+
```python
|
| 231 |
+
from trl import GRPOConfig
|
| 232 |
+
|
| 233 |
+
training_args = GRPOConfig(
|
| 234 |
+
loss_type="dr_grpo",
|
| 235 |
+
per_device_train_batch_size=1, # train_batch_size_per_device in the Training section of the repository
|
| 236 |
+
num_generations=8, # num_samples in the Training section of the repository
|
| 237 |
+
max_completion_length=3000, # generate_max_length in the Training section of the repository
|
| 238 |
+
beta=0.0, # β in the Training section of the repository
|
| 239 |
+
)
|
| 240 |
+
```
|
| 241 |
+
|
| 242 |
+
### Part I: Tricks or Traps? A Deep Dive into RL for LLM Reasoning (Lite PPO)
|
| 243 |
+
|
| 244 |
+
**📜 Paper**: https://huggingface.co/papers/2508.08221
|
| 245 |
+
|
| 246 |
+
The authors of this paper find that the combination of:
|
| 247 |
+
|
| 248 |
+
1. scaling rewards by the standard deviation computed over the entire batch and
|
| 249 |
+
2. aggregating loss over the total number of tokens
|
| 250 |
+
|
| 251 |
+
can unlock the learning capability of critic-free policies using vanilla PPO loss. Their results demonstrate that this simple combination consistently improves performance, surpassing strategies like GRPO and [DAPO](https://huggingface.co/papers/2503.14476).
|
| 252 |
+
|
| 253 |
+
TRL supports using these learnings to train a GRPO model by:
|
| 254 |
+
|
| 255 |
+
```python
|
| 256 |
+
from trl import GRPOConfig
|
| 257 |
+
|
| 258 |
+
training_args = GRPOConfig(
|
| 259 |
+
...
|
| 260 |
+
scale_rewards="batch",
|
| 261 |
+
loss_type="dapo",
|
| 262 |
+
# Other parameters used
|
| 263 |
+
beta=0.0, # = init_kl_coef in the paper
|
| 264 |
+
top_p=0.99,
|
| 265 |
+
top_k=100,
|
| 266 |
+
temperature=0.99,
|
| 267 |
+
num_generations=8, # = num_return_sequences in the paper
|
| 268 |
+
num_iterations=1, # = ppo_epochs in the paper
|
| 269 |
+
per_device_train_batch_size=4,
|
| 270 |
+
gradient_accumulation_steps=32,
|
| 271 |
+
steps_per_generation=8, # (rollout_batch_size*num_return_sequences) / (per_device_train_batch_size*gradient_accumulation_steps)
|
| 272 |
+
)
|
| 273 |
+
```
|
| 274 |
+
|
| 275 |
+
Note that when using gradient accumulation, the loss is aggregated over the total number of tokens in the batch, but not over the accumulated batch. For more details, see the [GRPO Trainer - Loss types](grpo_trainer#loss_types).
|
| 276 |
+
|
| 277 |
+
### Truncated Importance Sampling
|
| 278 |
+
|
| 279 |
+
**📰 Blog**: https://fengyao.notion.site/off-policy-rl
|
| 280 |
+
|
| 281 |
+
Online policy learning methods commonly use an optimized inference framework for rollout generation (e.g vLLM) that is separate from the training backend. This introduces a rollout-training mismatch, exemplified in the following PPO objective:
|
| 282 |
+
|
| 283 |
+
$$
|
| 284 |
+
\small{
|
| 285 |
+
\mathbb{E}_{a\sim\textcolor{red}{\pi_{\text{inference}}}(\theta_{\mathrm{old}})}
|
| 286 |
+
\Bigl[
|
| 287 |
+
\min\Bigl(
|
| 288 |
+
\frac{\textcolor{blue}{\pi_{\text{training}}}(a, \theta)}{\textcolor{blue}{\pi_{\text{training}}}(a, \theta_{\mathrm{old}})}\,\hat A,
|
| 289 |
+
\;\mathrm{clip}\bigl(\frac{\textcolor{blue}{\pi_{\text{training}}}(a, \theta)}{\textcolor{blue}{\pi_{\text{training}}}(a, \theta_{\mathrm{old}})},\,1-\epsilon,\,1+\epsilon\bigr)\,\hat A
|
| 290 |
+
\Bigr)
|
| 291 |
+
\Bigr]
|
| 292 |
+
}
|
| 293 |
+
$$
|
| 294 |
+
|
| 295 |
+
Despite \\( \textcolor{red}{\pi_{\text{inference}}} \\) and \\( \textcolor{blue}{\pi_{\text{training}}} \\) sharing the same model parameters \\( \theta \\), they can produce significantly different token probabilities. This unexpected behavior implicitly breaks the on-policy assumption, and silently turns training off-policy.
|
| 296 |
+
|
| 297 |
+
Truncated Importance Sampling (TIS) addresses this issue by adapting the model update via importance-sampling correction. The gradient computation of the aforementioned PPO objective becomes
|
| 298 |
+
|
| 299 |
+
$$
|
| 300 |
+
\small{
|
| 301 |
+
\mathbb{E}_{a\sim\textcolor{red}{\pi_{\text{inference}}}(\theta_{\mathrm{old}})}
|
| 302 |
+
\Bigl[
|
| 303 |
+
\underbrace{\min(\frac{\textcolor{blue}{\pi_{\text{training}}}(a, \theta_{\mathrm{old}})}{\textcolor{red}{\pi_{\text{inference}}}(a, \theta_{\mathrm{old}})}, C)}_{\text{truncated importance ratio}} \cdot
|
| 304 |
+
\nabla_\theta
|
| 305 |
+
\min\Bigl(
|
| 306 |
+
\frac{\textcolor{blue}{\pi_{\text{training}}}(a, \theta)}{\textcolor{blue}{\pi_{\text{training}}}(a, \theta_{\mathrm{old}})}\,\hat A,
|
| 307 |
+
\;\mathrm{clip}\bigl(\frac{\textcolor{blue}{\pi_{\text{training}}}(a, \theta)}{\textcolor{blue}{\pi_{\text{training}}}(a, \theta_{\mathrm{old}})},\,1-\epsilon,\,1+\epsilon\bigr)\,\hat A
|
| 308 |
+
\Bigr)
|
| 309 |
+
\Bigr]
|
| 310 |
+
}
|
| 311 |
+
$$
|
| 312 |
+
|
| 313 |
+
where \\( C \\) is a hyper-parameter. TIS is implemented in GRPO, and is enabled by selecting a `vllm_importance_sampling_mode` variant that includes the term `truncate`, such as `"sequence_truncate"` or `"token_truncate"`.
|
| 314 |
+
|
| 315 |
+
```python
|
| 316 |
+
from trl import GRPOConfig
|
| 317 |
+
|
| 318 |
+
training_args = GRPOConfig(
|
| 319 |
+
...
|
| 320 |
+
use_vllm=True,
|
| 321 |
+
vllm_importance_sampling_correction=True, # default True
|
| 322 |
+
vllm_importance_sampling_mode="sequence_truncate", # or "token_truncate"
|
| 323 |
+
vllm_importance_sampling_cap=2.0, # hyper-parameter C
|
| 324 |
+
)
|
| 325 |
+
```
|
| 326 |
+
|
| 327 |
+
### Masked Importance Sampling
|
| 328 |
+
|
| 329 |
+
**📰 Blog**: https://ringtech.notion.site/icepop
|
| 330 |
+
|
| 331 |
+
**📰 Blog**: https://yingru.notion.site/When-Speed-Kills-Stability-Demystifying-RL-Collapse-from-the-Training-Inference-Mismatch-271211a558b7808d8b12d403fd15edda
|
| 332 |
+
|
| 333 |
+
Masked Importance Sampling (MIS) addresses the same issue as [Truncated Importance Sampling](#truncated-importance-sampling) but replaces clipping with masking. MIS takes a more decisive stance by discarding updates whose discrepancy exceeds a threshold \\( C \\). We apply upper-side masking, so any ratio above \\( C \\) is removed from the update.
|
| 334 |
+
|
| 335 |
+
|
| 336 |
+
$$
|
| 337 |
+
\small{
|
| 338 |
+
\mathbb{E}_{a\sim\textcolor{red}{\pi_{\text{inference}}}(\theta_{\mathrm{old}})}
|
| 339 |
+
\Bigl[
|
| 340 |
+
\underbrace{\mathbf{1}\left[
|
| 341 |
+
\frac{\pi_{\text{training}}(a, \theta_{\mathrm{old}})}
|
| 342 |
+
{\pi_{\text{inference}}(a, \theta_{\mathrm{old}})}
|
| 343 |
+
\le C
|
| 344 |
+
\right]
|
| 345 |
+
\cdot
|
| 346 |
+
\frac{\pi_{\text{training}}(a, \theta_{\mathrm{old}})}
|
| 347 |
+
{\pi_{\text{inference}}(a, \theta_{\mathrm{old}})}}_{\text{masked importance ratio}} \cdot
|
| 348 |
+
\nabla_\theta
|
| 349 |
+
\min\Bigl(
|
| 350 |
+
\frac{\textcolor{blue}{\pi_{\text{training}}}(a, \theta)}{\textcolor{blue}{\pi_{\text{training}}}(a, \theta_{\mathrm{old}})}\,\hat A,
|
| 351 |
+
\;\mathrm{clip}\bigl(\frac{\textcolor{blue}{\pi_{\text{training}}}(a, \theta)}{\textcolor{blue}{\pi_{\text{training}}}(a, \theta_{\mathrm{old}})},\,1-\epsilon,\,1+\epsilon\bigr)\,\hat A
|
| 352 |
+
\Bigr)
|
| 353 |
+
\Bigr]
|
| 354 |
+
}
|
| 355 |
+
$$
|
| 356 |
+
|
| 357 |
+
MIS is implemented for GRPO, and is enabled by selecting a `vllm_importance_sampling_mode` variant that includes the term `"mask"`, such as `"sequence_mask"` or `"token_mask"`.
|
| 358 |
+
|
| 359 |
+
```python
|
| 360 |
+
from trl import GRPOConfig
|
| 361 |
+
|
| 362 |
+
training_args = GRPOConfig(
|
| 363 |
+
...
|
| 364 |
+
use_vllm=True,
|
| 365 |
+
vllm_importance_sampling_correction=True, # default True
|
| 366 |
+
vllm_importance_sampling_mode="sequence_mask", # or "token_mask"
|
| 367 |
+
vllm_importance_sampling_cap=2.0, # hyper-parameter C
|
| 368 |
+
)
|
| 369 |
+
```
|
| 370 |
+
|
| 371 |
+
### Sequence-level Importance Sampling
|
| 372 |
+
|
| 373 |
+
**📰 Blog**: https://yingru.notion.site/When-Speed-Kills-Stability-Demystifying-RL-Collapse-from-the-Training-Inference-Mismatch-271211a558b7808d8b12d403fd15edda
|
| 374 |
+
|
| 375 |
+
The theoretically principled way to correct for the training-inference distribution shift is importance sampling, as introduced in the two papers above [Truncated Importance Sampling](#truncated-importance-sampling) and [Masked Importance Sampling](#masked-importance-sampling). However, the choice of formulation is crucial for keeping the gradient unbiased and ensuring stable training.
|
| 376 |
+
|
| 377 |
+
This work shows that sequence-level importance sampling is the sound approach for addressing the training–inference mismatch. Although token-level importance sampling achieves lower variance than a sequence-level ratio, it introduces bias and is therefore argued to be unsuitable for autoregressive models. The token-level gradient estimator is
|
| 378 |
+
|
| 379 |
+
$$
|
| 380 |
+
\mathbb{E}_{x\sim\mathcal{D},\, y\sim \pi^{\text{inference}}_\theta(\cdot|x)}
|
| 381 |
+
\Bigg[
|
| 382 |
+
R(x,y)\,\cdot\,
|
| 383 |
+
\sum_{t=0}^{|y|-1}
|
| 384 |
+
\frac{\pi^{\text{training}}_\theta(y_t\,|\,x, y_{<t})}
|
| 385 |
+
{\pi^{\text{inference}}_\theta(y_t\,|\,x, y_{<t})}
|
| 386 |
+
\,\nabla_\theta \log \pi^{\text{training}}_\theta(y_t\,|\,x, y_{<t})
|
| 387 |
+
\Bigg]
|
| 388 |
+
$$
|
| 389 |
+
The correct, unbiased policy gradient estimator applies a single importance ratio over the entire generated sequence (trajectory) \\( y \\), The Sequence-Level IS estimator looks like:
|
| 390 |
+
|
| 391 |
+
$$
|
| 392 |
+
\mathbb{E}_{x\sim\mathcal{D},\, y\sim \pi^{\text{inference}}_\theta(\cdot|x)}
|
| 393 |
+
\Bigg[
|
| 394 |
+
\frac{\pi^{\text{training}}_\theta(y|x)}
|
| 395 |
+
{\pi^{\text{inference}}_\theta(y|x)}
|
| 396 |
+
\, R(x,y)\,
|
| 397 |
+
\nabla_\theta \log \pi^{\text{training}}_\theta(y|x)
|
| 398 |
+
\Bigg]
|
| 399 |
+
$$
|
| 400 |
+
|
| 401 |
+
TRL exposes the Importance Sampling granularity level through the `vllm_importance_sampling_mode` configuration parameter where `"sequence_*"` modes implement a sequence-level importance sampling ratio and `"token_*"` a per-token ratio.
|
| 402 |
+
|
| 403 |
+
### Sample More to Think Less: Group Filtered Policy Optimization for Concise Reasoning
|
| 404 |
+
|
| 405 |
+
**📜 Paper**: https://huggingface.co/papers/2508.09726
|
| 406 |
+
|
| 407 |
+
See [Experimental - GFPO](experimental#gfpo).
|
| 408 |
+
|
| 409 |
+
### Perception-Aware Policy Optimization for Multimodal Reasoning
|
| 410 |
+
|
| 411 |
+
**📜 Paper**: https://huggingface.co/papers/2507.06448
|
| 412 |
+
|
| 413 |
+
A novel policy gradient algorithm that encourages VLMs to learn to perceive while learning to reason. This is a TRL adaptation. The TRL implementation is not the official one provided by the authors.
|
| 414 |
+
This is a TRL adaptation of PAPO. Note that this is not the official implementation. The official code can be found in [MikeWangWZHL/PAPO](https://github.com/MikeWangWZHL/PAPO).
|
| 415 |
+
|
| 416 |
+
```python
|
| 417 |
+
from trl.experimental.papo import PAPOConfig, PAPOTrainer
|
| 418 |
+
|
| 419 |
+
training_args = PAPOConfig(
|
| 420 |
+
# PAPO-specific params
|
| 421 |
+
perception_loss_weight=0.01, # Weight for perception loss
|
| 422 |
+
mask_ratio=0.6, # 40% of image will be masked
|
| 423 |
+
mask_type="random", # Use patch masking (recommended)
|
| 424 |
+
der_loss_weight1=0.02,
|
| 425 |
+
der_loss_weight2=0.02,
|
| 426 |
+
# ...other GRPO params...
|
| 427 |
+
)
|
| 428 |
+
trainer = PAPOTrainer(
|
| 429 |
+
args=training_args,
|
| 430 |
+
...
|
| 431 |
+
)
|
| 432 |
+
```
|
| 433 |
+
|
| 434 |
+
### The Art of Scaling Reinforcement Learning
|
| 435 |
+
|
| 436 |
+
**📜 Paper**: https://huggingface.co/papers/2510.13786
|
| 437 |
+
|
| 438 |
+
A systematic study that defines a framework for analyzing and predicting reinforcement learning scaling in large language models, identifies key design choices that affect compute efficiency and propose a best-practice recipe called ScaleRL.
|
| 439 |
+
|
| 440 |
+
You can partially reproduce the ScaleRL recipe using the [`GRPOTrainer`] with the following configs:
|
| 441 |
+
|
| 442 |
+
```python
|
| 443 |
+
from trl import GRPOConfig
|
| 444 |
+
|
| 445 |
+
training_args = GRPOConfig(
|
| 446 |
+
loss_type="cispo",
|
| 447 |
+
epsilon_high=5.0,
|
| 448 |
+
num_generations=16,
|
| 449 |
+
scale_rewards="batch",
|
| 450 |
+
cast_lm_head_to_fp32=True
|
| 451 |
+
)
|
| 452 |
+
```
|
| 453 |
+
|
| 454 |
+
### It Takes Two: Your GRPO Is Secretly DPO
|
| 455 |
+
|
| 456 |
+
**📜 Paper**: https://huggingface.co/papers/2510.00977
|
| 457 |
+
|
| 458 |
+
Shows that GRPO's effectiveness stems from an implicit contrastive objective rather than accurate advantage estimation via large group sizes. This establishes a formal connection between GRPO and DPO, where group size only affects Monte Carlo estimators of the contrastive objective. The authors introduce 2-GRPO — using just two rollouts — which matches the performance of 16-GRPO at significantly lower training cost. Used in TRL via [`GRPOTrainer`] with `num_generations=2`. To reproduce the paper's setting, use this configuration:
|
| 459 |
+
|
| 460 |
+
```python
|
| 461 |
+
from trl import GRPOConfig, GRPOTrainer
|
| 462 |
+
|
| 463 |
+
training_args = GRPOConfig(
|
| 464 |
+
num_generations=2, # minimal two-rollout case (2-GRPO) from the paper
|
| 465 |
+
loss_type="grpo",
|
| 466 |
+
)
|
| 467 |
+
trainer = GRPOTrainer(
|
| 468 |
+
...,
|
| 469 |
+
args=training_args,
|
| 470 |
+
)
|
| 471 |
+
```
|
| 472 |
+
|
| 473 |
+
### Soft Adaptive Policy Optimization
|
| 474 |
+
|
| 475 |
+
**📜 Paper**: https://huggingface.co/papers/2511.20347
|
| 476 |
+
|
| 477 |
+
Soft Adaptive Policy Optimization (SAPO), replaces hard clipping with a smooth, temperature-controlled gate that adaptively attenuates off-policy updates while preserving useful learning signals. Compared with GSPO and GRPO, SAPO is both sequence-coherent and token-adaptive. Like GSPO, SAPO maintains sequence-level coherence, but its soft gating forms a continuous trust region that avoids the brittle hard clipping band used in GSPO.
|
| 478 |
+
|
| 479 |
+
To reproduce the paper's setting, use this configuration:
|
| 480 |
+
|
| 481 |
+
```python
|
| 482 |
+
from trl import GRPOConfig
|
| 483 |
+
|
| 484 |
+
training_args = GRPOConfig(
|
| 485 |
+
loss_type="sapo",
|
| 486 |
+
sapo_temperature_pos=1.0, # default value
|
| 487 |
+
sapo_temperature_neg=1.05, # default value
|
| 488 |
+
scale_rewards="group",
|
| 489 |
+
...
|
| 490 |
+
)
|
| 491 |
+
```
|
| 492 |
+
|
| 493 |
+
### DeepSeek-V3.2: Pushing the Frontier of Open Large Language Models
|
| 494 |
+
|
| 495 |
+
**📜 Paper**: https://huggingface.co/papers/2512.02556
|
| 496 |
+
|
| 497 |
+
DeepSeek-V3.2 technical report introduces several techniques to enhance the performance of GRPO. In TRL we implement:
|
| 498 |
+
|
| 499 |
+
- The **Unbiased KL Estimate**, which corrects the K3 estimator (as used in the original GRPO implementation) to obtain an unbiased KL estimate using the importance-sampling
|
| 500 |
+
ratio between the current policy \\( \pi_\theta \\) and the behavior policy \\( \pi_{\text{old}} \\).
|
| 501 |
+
|
| 502 |
+
$$
|
| 503 |
+
\mathrm{D}_{\mathrm{KL}}\!\left(\pi_\theta(o_{i,t}) \,\|\, \pi_{\text{ref}}(o_{i,t})\right) =
|
| 504 |
+
\textcolor{red}{\frac{\pi_\theta(o_{i,t}\mid q, o_{i,<t})}{\pi_{\text{old}}(o_{i,t}\mid q, o_{i,<t})}}
|
| 505 |
+
\left(
|
| 506 |
+
\frac{\pi_{\text{ref}}(o_{i,t}\mid q, o_{i,<t})}{\pi_\theta(o_{i,t}\mid q, o_{i,<t})}
|
| 507 |
+
-
|
| 508 |
+
\log \frac{\pi_{\text{ref}}(o_{i,t}\mid q, o_{i,<t})}{\pi_\theta(o_{i,t}\mid q, o_{i,<t})}
|
| 509 |
+
- 1
|
| 510 |
+
\right).
|
| 511 |
+
$$
|
| 512 |
+
|
| 513 |
+
To enable this feature, set the `use_bias_correction_kl` parameter to `True` in the [`GRPOConfig`], and `beta > 0`:
|
| 514 |
+
|
| 515 |
+
```python
|
| 516 |
+
from trl import GRPOConfig
|
| 517 |
+
|
| 518 |
+
training_args = GRPOConfig(
|
| 519 |
+
...,
|
| 520 |
+
beta=0.001, # the paper doesn't specify the value used, so we use the value from "DeepSeek-R1 incentivizes reasoning in LLMs through reinforcement learning"
|
| 521 |
+
use_bias_correction_kl=True,
|
| 522 |
+
)
|
| 523 |
+
```
|
| 524 |
+
|
| 525 |
+
- The **Off-Policy Masking**, which stabilizes training by ignoring sequences where the policy performs poorly (negative advantage) **and** has drifted significantly from the old policy (high KL divergence).
|
| 526 |
+
|
| 527 |
+
The off-policy binary mask \\(\textcolor{red}{M_{i,t}}\\) is defined as:
|
| 528 |
+
|
| 529 |
+
$$
|
| 530 |
+
\textcolor{red}{M_{i,t}} = \begin{cases}
|
| 531 |
+
0 & \text{if } \hat{A}_{i,t} < 0 \quad \text{and} \quad \frac{1}{|o_i|} \sum_{t=1}^{|o_i|} \log \frac{\pi_{\theta_{\text{old}}}(o_{i,t} \mid q, o_{i,<t})}{\pi_\theta(o_{i,t} \mid q, o_{i,<t})} > \textcolor{blue}{\delta} \\
|
| 532 |
+
1 & \text{otherwise}
|
| 533 |
+
\end{cases}
|
| 534 |
+
$$
|
| 535 |
+
|
| 536 |
+
This mask is then applied to the GRPO loss as follows:
|
| 537 |
+
|
| 538 |
+
$$
|
| 539 |
+
\mathcal{L}_{\text{GRPO}}(\theta) = -\frac{1}{G} \sum_{i=1}^G \frac{1}{|o_i|} \sum_{t=1}^{|o_i|} \left[ \min \left( \frac{\pi_\theta(o_{i,t} \mid q, o_{i,< t})}{\pi_{\theta_{\text{old}}}(o_{i,t} \mid q, o_{i,< t})} \hat{A}_{i,t}, \, \text{clip}\left( \frac{\pi_\theta(o_{i,t} \mid q, o_{i,< t})}{\pi_{\theta_{\text{old}}}(o_{i,t} \mid q, o_{i,< t})}, 1 - \epsilon, 1 + \epsilon \right) \hat{A}_{i,t} \right) \textcolor{red}{M_{i,t}} - \beta \mathbb{D}_{\text{KL}}\left[\pi_\theta \| \pi_{\text{ref}}\right] \right]
|
| 540 |
+
$$
|
| 541 |
+
|
| 542 |
+
To enable this feature, use the `off_policy_mask_threshold` (corresponding to \\( \textcolor{blue}{\delta} \\)) in the [`GRPOConfig`]:
|
| 543 |
+
|
| 544 |
+
```python
|
| 545 |
+
from trl import GRPOConfig
|
| 546 |
+
|
| 547 |
+
training_args = GRPOConfig(
|
| 548 |
+
...,
|
| 549 |
+
off_policy_mask_threshold=0.5,
|
| 550 |
+
)
|
| 551 |
+
```
|
| 552 |
+
|
| 553 |
+
While the paper doesn't specify a \\( \textcolor{blue}{\delta} \\) value used, a good starting point could be \\( \textcolor{blue}{\delta} = 0.5 \\). If training seems too conservative or too many sequences are masked, you can increase the value.
|
| 554 |
+
For reference, \\( \textcolor{blue}{\delta} = 1.0 \\) corresponds to an average log-ratio divergence of 1 nat per token, i.e. on sequences where this threshold is exceeded, the old policy was on average \\( e^1 \approx 2.7 \\) times more likely to generate these tokens than the current policy.
|
| 555 |
+
|
| 556 |
+
### GDPO: Group reward-Decoupled Normalization Policy Optimization for Multi-reward RL Optimization
|
| 557 |
+
|
| 558 |
+
**📜 Paper**: https://huggingface.co/papers/2601.05242
|
| 559 |
+
|
| 560 |
+
GDPO is a reinforcement learning optimization method designed for multi-reward training. While existing approaches commonly apply Group Relative Policy Optimization (GRPO) in multi-reward settings, the authors show that this leads to reward advantages collapse, reducing training signal resolution and causing unstable or failed convergence. GDPO resolves this issue by decoupling reward normalization across individual rewards, preserving their relative differences and enabling more faithful preference optimization. To enable GDPO for multi-reward RL training, simply set:
|
| 561 |
+
|
| 562 |
+
For a group of \\( N \\) rewards and \\( G \\) samples per group, GDPO normalizes each reward independently:
|
| 563 |
+
|
| 564 |
+
$$
|
| 565 |
+
A_n^{(i,j)} = \frac{r_n^{(i,j)} - \text{mean}\{r_n^{(i,1)}, \ldots, r_n^{(i,G)}\}}{\text{std}\{r_n^{(i,1)}, \ldots, r_n^{(i,G)}\} + \epsilon}
|
| 566 |
+
$$
|
| 567 |
+
|
| 568 |
+
The normalized group advantage is then aggregated across rewards:
|
| 569 |
+
|
| 570 |
+
$$
|
| 571 |
+
A^{(i,j)} = \sum_{n=1}^{N} w_n A_n^{(i,j)}
|
| 572 |
+
$$
|
| 573 |
+
|
| 574 |
+
The final per-batch normalization produces:
|
| 575 |
+
|
| 576 |
+
$$
|
| 577 |
+
\hat{A}^{(i,j)} = \frac{A^{(i,j)} - \text{mean}_{i',j'}\{A^{(i',j')}\}}{\text{std}_{i',j'}\{A^{(i',j')}\} + \epsilon}
|
| 578 |
+
$$
|
| 579 |
+
|
| 580 |
+
Here, \\( \text{mean}_{i',j'}\{A^{(i',j')}\} \\) and \\( \text{std}_{i',j'}\{A^{(i',j')}\} \\) denote statistics over all groups in the batch.
|
| 581 |
+
|
| 582 |
+
```python
|
| 583 |
+
from trl import GRPOConfig
|
| 584 |
+
|
| 585 |
+
|
| 586 |
+
training_args = GRPOConfig(
|
| 587 |
+
...,
|
| 588 |
+
multi_objective_aggregation="normalize_then_sum",
|
| 589 |
+
)
|
| 590 |
+
```
|
| 591 |
+
|
| 592 |
+
Note that this method only has an effect when training involve more than one reward function.
|
| 593 |
+
|
| 594 |
+
The authors provide a easy-to-use, slurm-free training example that enable the community to quickly validate GDPO’s effectiveness over GRPO, see [Experiment-"Aha" moment](https://github.com/NVlabs/GDPO/tree/main/trl-GDPO).
|
| 595 |
+
|
| 596 |
+
### Length-Unbiased Sequence Policy Optimization: Revealing and Controlling Response Length Variation in RLVR
|
| 597 |
+
|
| 598 |
+
**📜 Paper**: https://huggingface.co/papers/2602.05261
|
| 599 |
+
|
| 600 |
+
Length-Unbiased Sequence Policy Optimization (LUSPO) modifies GSPO by scaling each sequence's loss by its length. This corrects GSPO's gradient bias that penalizes longer responses. To reproduce the paper's setting, use this configuration:
|
| 601 |
+
|
| 602 |
+
```python
|
| 603 |
+
from trl import GRPOConfig
|
| 604 |
+
|
| 605 |
+
training_args = GRPOConfig(
|
| 606 |
+
loss_type="luspo",
|
| 607 |
+
importance_sampling_level="sequence",
|
| 608 |
+
epsilon=2e-3, # section 5.1 of the paper
|
| 609 |
+
epsilon_high=2.5e-3, # section 5.1 of the paper
|
| 610 |
+
)
|
| 611 |
+
```
|
| 612 |
+
|
| 613 |
+
### VESPO: Variational Sequence-Level Soft Policy Optimization for Stable Off-Policy LLM Training
|
| 614 |
+
|
| 615 |
+
**📜 Paper**: https://huggingface.co/papers/2602.10693
|
| 616 |
+
|
| 617 |
+
VESPO addresses training instability in off-policy RL caused by policy staleness, asynchronous updates, and train-inference mismatches. Rather than relying on heuristic token-level clipping (GRPO) or sequence-length normalization (GSPO), VESPO derives a principled reshaping kernel from a variational framework. In practice, this yields a smooth, asymmetric Gamma weighting function that gracefully suppresses extreme sequence-level importance weights without introducing length bias.
|
| 618 |
+
|
| 619 |
+
$$
|
| 620 |
+
\mathcal{L}_{\text{VESPO}}(\theta) = - \mathbb{E}_{\tau \sim \mu} \left[ \underbrace{W(\tau)^{k} \cdot \exp\left(\lambda
|
| 621 |
+
(1 - W(\tau))\right)}_{\phi(W) \text{ detached }} \cdot \mathcal{A}(\tau) \cdot \log \pi_\theta(\tau) \right]
|
| 622 |
+
$$
|
| 623 |
+
|
| 624 |
+
with \\( W(\tau) = \frac{\pi_\theta(\tau)}{\mu(\tau)} \\) the sequence level importance ratio, and \\( \phi(W) \\) is detached from the computation graph to serve as a gradient scaling coefficient.
|
| 625 |
+
|
| 626 |
+
```python
|
| 627 |
+
from trl import GRPOConfig
|
| 628 |
+
|
| 629 |
+
training_args = GRPOConfig(
|
| 630 |
+
loss_type="vespo",
|
| 631 |
+
use_vllm=True, # or False if not using any token-level `vllm_importance_sampling_correction` methods
|
| 632 |
+
vllm_importance_sampling_mode="token_truncate", # default correction mode for VESPO, `token_mask` also supported
|
| 633 |
+
vespo_k_pos=2.0, # power exponent (c1 in paper Section 3.4) for positive advantages
|
| 634 |
+
vespo_lambda_pos=3.0, # decay factor (c2 in paper Section 3.4) for positive advantages
|
| 635 |
+
vespo_k_neg=3.0, # power exponent (c1 in paper Section 3.4) for negative advantages
|
| 636 |
+
vespo_lambda_neg=2.0, # decay factor (c2 in paper Section 3.4) for negative advantages
|
| 637 |
+
)
|
| 638 |
+
```
|
| 639 |
+
|
| 640 |
+
|
| 641 |
+
### Rethinking the Trust Region in LLM Reinforcement Learning
|
| 642 |
+
|
| 643 |
+
**📜 Paper**: https://huggingface.co/papers/2602.04879
|
| 644 |
+
|
| 645 |
+
DPPO replaces PPO/GRPO's heuristic ratio-clipping with a principled trust region based on direct policy divergence estimates. PPO-style clipping masks tokens based on the probability ratio π/μ, which over-penalizes low-probability tokens and under-penalizes high-probability ones. DPPO instead masks based on direct approximations of policy divergence (TV or KL), ensuring updates stay within a theoretically grounded trust region. Four divergence approximations are supported: `binary_tv`, `binary_kl`, `topk_tv`, and `topk_kl`.
|
| 646 |
+
|
| 647 |
+
```python
|
| 648 |
+
from trl.experimental.dppo import DPPOConfig, DPPOTrainer
|
| 649 |
+
|
| 650 |
+
training_args = DPPOConfig(
|
| 651 |
+
divergence_type="binary_tv", # divergence approximation
|
| 652 |
+
divergence_topk=20, # K for top-K divergence modes (Section 7 / Appendix G.2 of the paper)
|
| 653 |
+
epsilon=0.15, # δ_low threshold (Appendix F of the paper)
|
| 654 |
+
epsilon_high=0.15, # δ_high threshold (Appendix F of the paper)
|
| 655 |
+
clip_ratio_c=20.0, # IS ratio upper bound C (Section 5.4 of the paper)
|
| 656 |
+
beta=0.0, # KL regularization coefficient
|
| 657 |
+
use_vllm=True,
|
| 658 |
+
)
|
| 659 |
+
|
| 660 |
+
trainer = DPPOTrainer(
|
| 661 |
+
model="your-model",
|
| 662 |
+
reward_funcs=[...],
|
| 663 |
+
args=training_args,
|
| 664 |
+
train_dataset=dataset,
|
| 665 |
+
)
|
| 666 |
+
trainer.train()
|
| 667 |
+
```
|
| 668 |
+
|
| 669 |
+
The official code [sail-sg/Stable-RL](https://github.com/sail-sg/Stable-RL)
|
| 670 |
+
|
| 671 |
+
## Direct Policy Optimization
|
| 672 |
+
|
| 673 |
+
Papers relating to the [`DPOTrainer`]
|
| 674 |
+
|
| 675 |
+
### Direct Preference Optimization: Your Language Model is Secretly a Reward Model
|
| 676 |
+
|
| 677 |
+
**📜 Paper**: https://huggingface.co/papers/2305.18290
|
| 678 |
+
|
| 679 |
+
Direct Preference Optimization (DPO) fine-tunes language models more efficiently and with better performance compared to reinforcement learning from human feedback (RLHF), by directly optimizing policy training based on human preferences. To reproduce the paper's setting, use this configuration:
|
| 680 |
+
|
| 681 |
+
```python
|
| 682 |
+
from trl import DPOConfig
|
| 683 |
+
|
| 684 |
+
training_args = DPOConfig(
|
| 685 |
+
loss_type="sigmoid", # losses in Appendix B of the paper
|
| 686 |
+
per_device_train_batch_size=64, # batch size in Appendix B of the paper
|
| 687 |
+
learning_rate=1e-6, # learning rate in Appendix B of the paper
|
| 688 |
+
beta=0.1, # β in Appendix B of the paper
|
| 689 |
+
)
|
| 690 |
+
```
|
| 691 |
+
|
| 692 |
+
### SLiC-HF: Sequence Likelihood Calibration with Human Feedback
|
| 693 |
+
|
| 694 |
+
**📜 Paper**: https://huggingface.co/papers/2305.10425
|
| 695 |
+
|
| 696 |
+
Sequence Likelihood Calibration (SLiC) is shown to be an effective and simpler alternative to Reinforcement Learning from Human Feedback (RLHF) for learning from human preferences in language models. To reproduce the paper's setting, use this configuration:
|
| 697 |
+
|
| 698 |
+
```python
|
| 699 |
+
from trl import DPOConfig
|
| 700 |
+
|
| 701 |
+
training_args = DPOConfig(
|
| 702 |
+
loss_type="hinge", # Section 2 of the paper
|
| 703 |
+
per_device_train_batch_size=512, # batch size in Section 3.2 of the paper
|
| 704 |
+
learning_rate=1e-4, # learning rate in Section 3.2 of the paper
|
| 705 |
+
)
|
| 706 |
+
```
|
| 707 |
+
|
| 708 |
+
These parameters only appear in the [published version](https://openreview.net/pdf?id=0qSOodKmJaN)
|
| 709 |
+
|
| 710 |
+
### Statistical Rejection Sampling Improves Preference Optimization
|
| 711 |
+
|
| 712 |
+
**📜 Paper**: https://huggingface.co/papers/2309.06657
|
| 713 |
+
|
| 714 |
+
Proposes **RSO**, selecting stronger preference pairs via statistical rejection sampling to boost offline preference optimization; complements DPO/SLiC. They also introduce a new loss defined as:
|
| 715 |
+
|
| 716 |
+
$$
|
| 717 |
+
\mathcal{L}_{\text{hinge-norm}}(\pi_\theta)
|
| 718 |
+
= \mathbb{E}_{(x, y_w, y_l) \sim \mathcal{D}}
|
| 719 |
+
\left[
|
| 720 |
+
\max\left(0,\; 1 - \left[\gamma \log \frac{\pi_\theta(y_w \mid x)}{\pi_\text{ref}(y_w \mid x)} - \gamma \log \frac{\pi_\theta(y_l \mid x)}{\pi_\text{ref}(y_l \mid x)}\right]\right)
|
| 721 |
+
\right]
|
| 722 |
+
$$
|
| 723 |
+
|
| 724 |
+
To train with RSO-filtered data and the hinge-norm loss, you can use the following code:
|
| 725 |
+
|
| 726 |
+
```python
|
| 727 |
+
from trl import DPOConfig, DPOTrainer
|
| 728 |
+
|
| 729 |
+
dataset = ...
|
| 730 |
+
|
| 731 |
+
def rso_accept(example): # replace with your actual filter/score logic
|
| 732 |
+
return example["rso_keep"]
|
| 733 |
+
|
| 734 |
+
train_dataset = train_dataset.filter(rso_accept)
|
| 735 |
+
|
| 736 |
+
training_args = DPOConfig(
|
| 737 |
+
loss_type="hinge",
|
| 738 |
+
beta=0.05, # correspond to γ in the paper
|
| 739 |
+
)
|
| 740 |
+
|
| 741 |
+
trainer = DPOTrainer(
|
| 742 |
+
...,
|
| 743 |
+
args=training_args,
|
| 744 |
+
train_dataset=train_dataset,
|
| 745 |
+
)
|
| 746 |
+
trainer.train()
|
| 747 |
+
```
|
| 748 |
+
|
| 749 |
+
### Beyond Reverse KL: Generalizing Direct Preference Optimization with Diverse Divergence Constraints
|
| 750 |
+
|
| 751 |
+
**📜 Paper**: https://huggingface.co/papers/2309.16240
|
| 752 |
+
|
| 753 |
+
Proposes \(( f \\)-DPO, extending DPO by replacing the usual reverse-KL regularizer with a general \(( f \\)-divergence, letting you trade off mode-seeking vs mass-covering behavior (e.g. forward KL, JS, \(( \alpha \\)-divergences). The only change is replacing the DPO log-ratio margin with an **f′ score**:
|
| 754 |
+
|
| 755 |
+
$$
|
| 756 |
+
\mathcal{L}_{f\text{-DPO}}(\pi_\theta)
|
| 757 |
+
= \mathbb{E}_{(x, y_w, y_l) \sim \mathcal{D}}
|
| 758 |
+
\left[
|
| 759 |
+
-\log \sigma\left(
|
| 760 |
+
\beta \textcolor{red}{f'}\textcolor{red}{\Big(}\frac{\pi_\theta(y_w|x)}{\pi_{\text{ref}}(y_w|x)}\textcolor{red}{\Big)}
|
| 761 |
+
-
|
| 762 |
+
\beta \textcolor{red}{f'}\textcolor{red}{\Big(}\frac{\pi_\theta(y_l|x)}{\pi_{\text{ref}}(y_l|x)}\textcolor{red}{\Big)}
|
| 763 |
+
\right)
|
| 764 |
+
\right]
|
| 765 |
+
$$
|
| 766 |
+
|
| 767 |
+
Where \\( f' \\) is the derivative of the convex function defining the chosen \(( f \\)-divergence.
|
| 768 |
+
|
| 769 |
+
To reproduce:
|
| 770 |
+
|
| 771 |
+
```python
|
| 772 |
+
from trl import DPOConfig
|
| 773 |
+
|
| 774 |
+
training_args = DPOConfig(
|
| 775 |
+
loss_type="sigmoid",
|
| 776 |
+
beta=0.1,
|
| 777 |
+
f_divergence_type="js_divergence", # or "reverse_kl" (default), "forward_kl", "js_divergence", "alpha_divergence"
|
| 778 |
+
f_alpha_divergence_coef=0.5, # only used if f_divergence_type="alpha_divergence"
|
| 779 |
+
)
|
| 780 |
+
```
|
| 781 |
+
|
| 782 |
+
### A General Theoretical Paradigm to Understand Learning from Human Preferences
|
| 783 |
+
|
| 784 |
+
**📜 Paper**: https://huggingface.co/papers/2310.12036
|
| 785 |
+
|
| 786 |
+
Learning from human preferences can be written as a single KL-regularized objective over pairwise preference probabilities,
|
| 787 |
+
|
| 788 |
+
$$
|
| 789 |
+
\max_\pi ;\mathbb{E}\big[\Psi\left(p^*(y \succ y' \mid x)\right)\big] - \tau\mathrm{KL}(\pi||\pi_{\text{ref}}),
|
| 790 |
+
$$
|
| 791 |
+
|
| 792 |
+
which reveals RLHF and DPO as special cases corresponding to the logit choice of \\( \Psi \\).
|
| 793 |
+
The paper shows that this logit transform amplifies near-deterministic preferences and effectively weakens KL regularization, explaining overfitting.
|
| 794 |
+
Using the **Identity transform (IPO)** avoids this pathology by optimizing preferences directly, without assuming a Bradley–Terry reward model.
|
| 795 |
+
To reproduce the paper's setting, use this configuration:
|
| 796 |
+
|
| 797 |
+
```python
|
| 798 |
+
from trl import DPOConfig
|
| 799 |
+
|
| 800 |
+
training_args = DPOConfig(
|
| 801 |
+
loss_type="ipo", # Section 5.1 of the paper
|
| 802 |
+
per_device_train_batch_size=90, # mini-batch size in Section C.1 of the paper
|
| 803 |
+
learning_rate=1e-2, # learning rate in Section C.1 of the paper
|
| 804 |
+
)
|
| 805 |
+
```
|
| 806 |
+
|
| 807 |
+
These parameters only appear in the [published version](https://proceedings.mlr.press/v238/gheshlaghi-azar24a/gheshlaghi-azar24a.pdf)
|
| 808 |
+
|
| 809 |
+
### Towards Efficient and Exact Optimization of Language Model Alignment
|
| 810 |
+
|
| 811 |
+
**📜 Paper**: https://huggingface.co/papers/2402.00856
|
| 812 |
+
|
| 813 |
+
The paper shows that direct preference methods like DPO optimize the wrong KL direction, leading to blurred preference capture, and proposes EXO as an efficient way to exactly optimize the human‑preference alignment objective by leveraging reverse KL probability matching rather than forward KL approximations. To reproduce the paper's setting, use this configuration:
|
| 814 |
+
|
| 815 |
+
```python
|
| 816 |
+
from trl import DPOConfig
|
| 817 |
+
|
| 818 |
+
training_args = DPOConfig(
|
| 819 |
+
loss_type="exo_pair", # Section 3.2 of the paper
|
| 820 |
+
# From Section B of the paper
|
| 821 |
+
per_device_train_batch_size=64,
|
| 822 |
+
learning_rate=1e-6,
|
| 823 |
+
beta=0.1,
|
| 824 |
+
)
|
| 825 |
+
```
|
| 826 |
+
|
| 827 |
+
### Noise Contrastive Alignment of Language Models with Explicit Rewards
|
| 828 |
+
|
| 829 |
+
**📜 Paper**: https://huggingface.co/papers/2402.05369
|
| 830 |
+
|
| 831 |
+
The paper reframes language-model alignment as a *noise-contrastive classification* problem, proposing InfoNCA to learn a policy from explicit rewards (or preferences) by matching a reward-induced target distribution over responses, and showing DPO is a special binary case. It then introduces NCA, which adds an absolute likelihood term to prevent the likelihood collapse seen in purely relative (contrastive) objectives.
|
| 832 |
+
|
| 833 |
+
With pairwise preferences, treat the chosen/rejected \\( K=2 \\), define scores \\( r=\beta(\log\pi_\theta-\log\pi_{\text{ref}}) \\), and apply the NCA preference loss \\( -\log\sigma(r_w)-\tfrac12\log\sigma(-r_w)-\tfrac12\log\sigma(-r_l) \\).
|
| 834 |
+
|
| 835 |
+
To reproduce the paper's setting, use this configuration:
|
| 836 |
+
|
| 837 |
+
```python
|
| 838 |
+
from trl import DPOConfig
|
| 839 |
+
|
| 840 |
+
training_args = DPOConfig(
|
| 841 |
+
loss_type="nca_pair",
|
| 842 |
+
# From Section C of the paper
|
| 843 |
+
per_device_train_batch_size=32,
|
| 844 |
+
learning_rate=5e-6,
|
| 845 |
+
beta=0.01,
|
| 846 |
+
)
|
| 847 |
+
```
|
| 848 |
+
|
| 849 |
+
### Provably Robust DPO: Aligning Language Models with Noisy Feedback
|
| 850 |
+
|
| 851 |
+
**📜 Paper**: https://huggingface.co/papers/2403.00409
|
| 852 |
+
|
| 853 |
+
DPO breaks under noisy human preferences because label flips bias the objective. Robust DPO fixes this by analytically debiasing the DPO loss under a simple noise model, with provable guarantees.
|
| 854 |
+
|
| 855 |
+
$$
|
| 856 |
+
\mathcal{L}_{\text{robust}}(\pi_\theta) = \frac{(1-\varepsilon)\mathcal{L}_{\text{DPO}}(y_w, y_l) - \varepsilon\mathcal{L}_{\text{DPO}}(y_l, y_w)}
|
| 857 |
+
{1-2\varepsilon}
|
| 858 |
+
$$
|
| 859 |
+
|
| 860 |
+
Where \\( \mathcal{L}_{\text{DPO}} \\) is the DPO loss defined in [Direct Preference Optimization: Your Language Model is Secretly a Reward Model](#direct-preference-optimization-your-language-model-is-secretly-a-reward-model) and \\( \varepsilon \\) is the probability of a label flip.
|
| 861 |
+
|
| 862 |
+
This single correction turns noisy preference data into an unbiased estimator of the clean DPO objective.
|
| 863 |
+
|
| 864 |
+
```python
|
| 865 |
+
from trl import DPOConfig
|
| 866 |
+
|
| 867 |
+
training_args = DPOConfig(
|
| 868 |
+
loss_type="robust",
|
| 869 |
+
per_device_train_batch_size=16, # batch size in Section B of the paper
|
| 870 |
+
learning_rate=1e-3, # learning rate in Section B of the paper
|
| 871 |
+
beta=0.1, # β in Section B of the paper,
|
| 872 |
+
max_length=512, # max length in Section B of the paper
|
| 873 |
+
label_smoothing=0.1 # label smoothing $\varepsilon$ in Section 6 of the paper
|
| 874 |
+
)
|
| 875 |
+
```
|
| 876 |
+
|
| 877 |
+
### Binary Classifier Optimization for Large Language Model Alignment
|
| 878 |
+
|
| 879 |
+
**📜 Paper**: https://huggingface.co/papers/2404.04656
|
| 880 |
+
|
| 881 |
+
Theoretical analysis and a new algorithm, Binary Classifier Optimization, explain and enhance the alignment of large language models using binary feedback signals. To reproduce the paper's setting, use this configuration:
|
| 882 |
+
|
| 883 |
+
BCO reframes language-model alignment as behavioral cloning from an optimal reward-weighted distribution, yielding simple supervised objectives that avoid RL while remaining theoretically grounded.
|
| 884 |
+
It supports both unpaired reward data and pairwise preference data, with a reward-shift–invariant formulation that reduces to a DPO-style loss in the preference setting.
|
| 885 |
+
|
| 886 |
+
For the pairwise preference setting, the BCO loss is defined as:
|
| 887 |
+
|
| 888 |
+
$$
|
| 889 |
+
\mathcal{L}_{\text{bco\_pair}}(\pi_\theta) =
|
| 890 |
+
\mathbb{E}_{(x, y_w, y_l) \sim \mathcal{D}}
|
| 891 |
+
\left[
|
| 892 |
+
-\log \sigma\Big(
|
| 893 |
+
\beta[(\log\pi_\theta-\log\pi_{\text{ref}})(y_w)
|
| 894 |
+
-
|
| 895 |
+
(\log\pi_\theta-\log\pi_{\text{ref}})(y_l)]
|
| 896 |
+
\Big)
|
| 897 |
+
\right]
|
| 898 |
+
$$
|
| 899 |
+
|
| 900 |
+
To reproduce the paper in this setting, use this configuration:
|
| 901 |
+
|
| 902 |
+
```python
|
| 903 |
+
from trl import DPOConfig
|
| 904 |
+
|
| 905 |
+
training_args = DPOConfig(
|
| 906 |
+
loss_type="bco_pair",
|
| 907 |
+
# From Section C of the paper
|
| 908 |
+
per_device_train_batch_size=128,
|
| 909 |
+
learning_rate=5e-7,
|
| 910 |
+
beta=0.01,
|
| 911 |
+
)
|
| 912 |
+
```
|
| 913 |
+
|
| 914 |
+
For the unpaired version, the user should utilize [`experimental.bco.BCOConfig`] and [`experimental.bco.BCOTrainer`].
|
| 915 |
+
|
| 916 |
+
### Learn Your Reference Model for Real Good Alignment
|
| 917 |
+
|
| 918 |
+
**📜 Paper**: https://huggingface.co/papers/2404.09656
|
| 919 |
+
|
| 920 |
+
Trust Region DPO (TR-DPO) updates the reference policy during training, demonstrating effectiveness against DPO on the Anthropic HH and TLDR datasets, outperforming DPO by up to 19% measured by automatic evaluation with GPT-4, improving coherence, correctness, level of detail, helpfulness, and harmlessness. To reproduce the paper's setting, use this configuration:
|
| 921 |
+
|
| 922 |
+
```python
|
| 923 |
+
from trl import DPOConfig
|
| 924 |
+
|
| 925 |
+
training_args = DPOConfig(
|
| 926 |
+
sync_ref_model=True, # enable TR-DPO (Section 3 of the paper)
|
| 927 |
+
ref_model_mixup_alpha=0.6, # α soft update weight (Table 1 of the paper)
|
| 928 |
+
ref_model_sync_steps=512, # τ update frequency in steps (Table 1 of the paper)
|
| 929 |
+
beta=0.05, # β temperature (Table 1 of the paper)
|
| 930 |
+
learning_rate=1e-6, # learning rate (Table 2 of the paper)
|
| 931 |
+
num_train_epochs=1, # Table 2 of the paper
|
| 932 |
+
max_length=1024, # max tokens length (Table 2 of the paper)
|
| 933 |
+
max_grad_norm=2, # max gradient norm (Table 2 of the paper)
|
| 934 |
+
warmup_steps=100, # warm-up steps (Table 2 of the paper)
|
| 935 |
+
)
|
| 936 |
+
```
|
| 937 |
+
|
| 938 |
+
### Iterative Reasoning Preference Optimization
|
| 939 |
+
|
| 940 |
+
**📜 Paper**: https://huggingface.co/papers/2404.19733
|
| 941 |
+
|
| 942 |
+
Iterative RPO improves reasoning by repeatedly generating chain-of-thought candidates, building preference pairs from correct vs. incorrect answers, and training with a DPO + NLL objective. The extra NLL term is key for learning to actually generate winning traces.
|
| 943 |
+
|
| 944 |
+
TRL can express the DPO + NLL objective by mixing `"sigmoid"` (DPO) with `"sft"` (NLL):
|
| 945 |
+
|
| 946 |
+
```python
|
| 947 |
+
from trl import DPOConfig, DPOTrainer
|
| 948 |
+
|
| 949 |
+
training_args = DPOConfig(
|
| 950 |
+
loss_type=["sigmoid", "sft"],
|
| 951 |
+
loss_weights=[1.0, 1.0], # alpha in the paper, recommended value is 1.0
|
| 952 |
+
)
|
| 953 |
+
trainer = DPOTrainer(
|
| 954 |
+
...,
|
| 955 |
+
args=training_args,
|
| 956 |
+
)
|
| 957 |
+
```
|
| 958 |
+
|
| 959 |
+
Note that the paper uses an iterative loop: each iteration regenerates CoT candidates with the current model, then retrains on fresh preference pairs. TRL does not automate that loop for you.
|
| 960 |
+
|
| 961 |
+
### Self-Play Preference Optimization for Language Model Alignment
|
| 962 |
+
|
| 963 |
+
**📜 Paper**: https://huggingface.co/papers/2405.00675
|
| 964 |
+
|
| 965 |
+
A self-play method called SPPO for language model alignment achieves state-of-the-art performance by approximating Nash equilibrium policy in a constant-sum game setting, outperforming other approaches with limited data. To reproduce the paper's setting, use this configuration:
|
| 966 |
+
|
| 967 |
+
```python
|
| 968 |
+
from trl import DPOConfig
|
| 969 |
+
|
| 970 |
+
training_args = DPOConfig(
|
| 971 |
+
loss_type="sppo_hard",
|
| 972 |
+
# From Section 5 of the paper
|
| 973 |
+
beta=0.001, # β = η^−1
|
| 974 |
+
per_device_train_batch_size=64,
|
| 975 |
+
learning_rate=5e-7,
|
| 976 |
+
)
|
| 977 |
+
```
|
| 978 |
+
|
| 979 |
+
### Provably Mitigating Overoptimization in RLHF: Your SFT Loss is Implicitly an Adversarial Regularizer
|
| 980 |
+
|
| 981 |
+
**📜 Paper**: https://huggingface.co/papers/2405.16436
|
| 982 |
+
|
| 983 |
+
Regularized Preference Optimization (RPO) mitigates overoptimization in RLHF by fusing the DPO loss with the SFT loss, provably preventing the policy from choosing actions with spurious high proxy rewards. To reproduce the paper's setting, use this configuration:
|
| 984 |
+
|
| 985 |
+
```python
|
| 986 |
+
from trl import DPOConfig
|
| 987 |
+
|
| 988 |
+
training_args = DPOConfig(
|
| 989 |
+
loss_type=["sigmoid", "sft"], # RPO loss = DPO + SFT (Section 5 of the paper)
|
| 990 |
+
loss_weights=[1.0, 0.005], # η=0.005 SFT weight in Appendix E.1 of the paper
|
| 991 |
+
beta=0.01, # β in Appendix E.1 of the paper
|
| 992 |
+
learning_rate=5e-7, # learning rate in Appendix E.1 of the paper
|
| 993 |
+
num_train_epochs=1, # Appendix E.1 of the paper
|
| 994 |
+
)
|
| 995 |
+
```
|
| 996 |
+
|
| 997 |
+
### Distributional Preference Alignment of LLMs via Optimal Transport
|
| 998 |
+
|
| 999 |
+
**📜 Paper**: https://huggingface.co/papers/2406.05882
|
| 1000 |
+
|
| 1001 |
+
Alignment via Optimal Transport (AOT) aligns large language models distributionally by penalizing violations of stochastic dominance between positive and negative sample distributions, achieving state-of-the-art performance on alignment benchmarks. To reproduce the paper's setting, use this configuration:
|
| 1002 |
+
|
| 1003 |
+
```python
|
| 1004 |
+
from trl import DPOConfig
|
| 1005 |
+
|
| 1006 |
+
training_args = DPOConfig(
|
| 1007 |
+
loss_type="aot",
|
| 1008 |
+
beta=0.01, # from the caption of Figure 2
|
| 1009 |
+
)
|
| 1010 |
+
```
|
| 1011 |
+
|
| 1012 |
+
or, for the unpaired version:
|
| 1013 |
+
|
| 1014 |
+
```python
|
| 1015 |
+
from trl import DPOConfig
|
| 1016 |
+
|
| 1017 |
+
training_args = DPOConfig(
|
| 1018 |
+
loss_type="aot_unpaired",
|
| 1019 |
+
beta=0.01, # from the caption of Figure 2
|
| 1020 |
+
)
|
| 1021 |
+
```
|
| 1022 |
+
|
| 1023 |
+
There is no additional hyperparameter in the paper.
|
| 1024 |
+
|
| 1025 |
+
### Discovering Preference Optimization Algorithms with and for Large Language Models
|
| 1026 |
+
|
| 1027 |
+
**📜 Paper**: https://huggingface.co/papers/2406.08414
|
| 1028 |
+
|
| 1029 |
+
An LLM-driven method automatically discovers performant preference optimization algorithms, leading to a new algorithm called DiscoPOP that blends logistic and exponential losses. To reproduce the paper's setting, use this configuration:
|
| 1030 |
+
|
| 1031 |
+
```python
|
| 1032 |
+
from trl import DPOConfig
|
| 1033 |
+
|
| 1034 |
+
training_args = DPOConfig(
|
| 1035 |
+
loss_type="discopop",
|
| 1036 |
+
per_device_train_batch_size=64, # batch size in Section B.1 of the paper
|
| 1037 |
+
learning_rate=5e-7, # learning rate in Section B.1 of the paper
|
| 1038 |
+
beta=0.05, # β in Section B.1 of the paper,
|
| 1039 |
+
discopop_tau=0.05 # τ in Section E of the paper
|
| 1040 |
+
)
|
| 1041 |
+
```
|
| 1042 |
+
|
| 1043 |
+
### WPO: Enhancing RLHF with Weighted Preference Optimization
|
| 1044 |
+
|
| 1045 |
+
**📜 Paper**: https://huggingface.co/papers/2406.11827
|
| 1046 |
+
|
| 1047 |
+
WPO reweights preference pairs by their policy probabilities to reduce the off-policy gap in DPO-style training. The loss is:
|
| 1048 |
+
|
| 1049 |
+
$$
|
| 1050 |
+
\mathcal{L}_{\text{WPO}} = -\mathbb{E}_{(x, y_w, y_l) \sim \mathcal{D}} \left[ \textcolor{red}{w(x, y_w) w(x, y_l)} \log p(y_w \succ y_l \mid x) \right]
|
| 1051 |
+
$$
|
| 1052 |
+
|
| 1053 |
+
where the weight \\( w(x, y) \\) is defined as:
|
| 1054 |
+
|
| 1055 |
+
$$
|
| 1056 |
+
w(x, y) = \exp\left(\frac{1}{|y|}\sum_{t=1}^{|y|} \log \frac{\pi_\theta(y_t \mid x, y_{<t})}{\sum_{v \in \mathcal{V}} \pi_\theta(v \mid x, y_{<t})^2}\right)
|
| 1057 |
+
$$
|
| 1058 |
+
|
| 1059 |
+
To reproduce the paper's setting, use this configuration:
|
| 1060 |
+
|
| 1061 |
+
```python
|
| 1062 |
+
from trl import DPOConfig
|
| 1063 |
+
|
| 1064 |
+
training_args = DPOConfig(
|
| 1065 |
+
loss_type="sigmoid", # DPO loss used in the paper
|
| 1066 |
+
beta=0.01, # Section 4 of the paper
|
| 1067 |
+
use_weighting=True,
|
| 1068 |
+
)
|
| 1069 |
+
```
|
| 1070 |
+
|
| 1071 |
+
### Anchored Preference Optimization and Contrastive Revisions: Addressing Underspecification in Alignment
|
| 1072 |
+
|
| 1073 |
+
**📜 Paper**: https://huggingface.co/papers/2408.06266
|
| 1074 |
+
|
| 1075 |
+
CLAIR and APO enhance LLM alignment through more contrastive preference pairs and controlled alignment objectives, improving model performance close to GPT4-turbo. To reproduce the paper's setting, use this configuration:
|
| 1076 |
+
|
| 1077 |
+
```python
|
| 1078 |
+
from trl import DPOConfig
|
| 1079 |
+
|
| 1080 |
+
training_args = DPOConfig(
|
| 1081 |
+
loss_type="apo_zero", # Section 4 of the paper
|
| 1082 |
+
per_device_train_batch_size=64, # batch size in Section B.1 of the paper
|
| 1083 |
+
learning_rate=2e-7, # learning rate in Section 5.2 of the paper
|
| 1084 |
+
beta=0.1, # β in Section 5.2 of the paper,
|
| 1085 |
+
)
|
| 1086 |
+
```
|
| 1087 |
+
|
| 1088 |
+
```python
|
| 1089 |
+
from trl import DPOConfig
|
| 1090 |
+
|
| 1091 |
+
training_args = DPOConfig(
|
| 1092 |
+
loss_type="apo_down", # Section 4 of the paper
|
| 1093 |
+
per_device_train_batch_size=64, # batch size in Section B.1 of the paper
|
| 1094 |
+
learning_rate=2e-7, # learning rate in Section 5.2 of the paper
|
| 1095 |
+
beta=0.1, # β in Section 5.2 of the paper,
|
| 1096 |
+
)
|
| 1097 |
+
```
|
| 1098 |
+
|
| 1099 |
+
These parameters only appear in the [published version](https://aclanthology.org/2025.tacl-1.22.pdf)
|
| 1100 |
+
|
| 1101 |
+
### Length Desensitization in Direct Preference Optimization
|
| 1102 |
+
|
| 1103 |
+
**📜 Paper**: https://huggingface.co/papers/2409.06411
|
| 1104 |
+
|
| 1105 |
+
Shows that standard DPO is inherently length-sensitive, which often pushes models toward overly long or verbose generations. The paper proposes LD-DPO, which modifies the sequence log-prob aggregation by splitting the longer response into a shared prefix (up to the shorter response length) and an excess tail, then downweighting the tail with a factor \\( \alpha \in [0,1] \\):
|
| 1106 |
+
|
| 1107 |
+
$$
|
| 1108 |
+
\log \pi_\theta(y_{\text{long}}|x) = \log \pi_\theta(y_{1:l_p}|x) + \alpha \cdot \log \pi_\theta(y_{l_p+1:l}|x, y_{1:l_p}),
|
| 1109 |
+
\quad
|
| 1110 |
+
l_p=\min(|y_w|,|y_l|).
|
| 1111 |
+
$$
|
| 1112 |
+
|
| 1113 |
+
Setting \\( \alpha=1 \\) recovers standard \\( \alpha \\) reduces verbosity while preserving preference quality.
|
| 1114 |
+
The optimal \\( \alpha \\) depends on the model family and whether you’re training a base vs. instruct model, but the paper suggests \\( \alpha=0.5 \\) as a strong default starting point.
|
| 1115 |
+
|
| 1116 |
+
```python
|
| 1117 |
+
from trl import DPOConfig
|
| 1118 |
+
|
| 1119 |
+
training_args = DPOConfig(
|
| 1120 |
+
ld_alpha=0.5,
|
| 1121 |
+
)
|
| 1122 |
+
```
|
| 1123 |
+
|
| 1124 |
+
### Enhancing the Reasoning Ability of Multimodal Large Language Models via Mixed Preference Optimization
|
| 1125 |
+
|
| 1126 |
+
**📜 Paper**: https://huggingface.co/papers/2411.10442
|
| 1127 |
+
|
| 1128 |
+
Introduces Mixed Preference Optimization (MPO) to improve multimodal reasoning in MLLMs, addressing distribution shift and weak Chain-of-Thought (CoT) after standard pre-training and SFT. The paper contributes (1) MMPR, an automated pipeline for high-quality multimodal preference data, and (2) MPO, a combined preference objective (pairwise + BCO-style + SFT) that boosts CoT. InternVL2-8B-MPO reaches 67.0 on MathVista (+8.7 over InternVL2-8B), comparable to the 10× larger InternVL2-76B. Used in TRL via [`DPOConfig`] with composite loss. To reproduce the paper's setting, use this configuration:
|
| 1129 |
+
|
| 1130 |
+
```python
|
| 1131 |
+
from trl import DPOConfig
|
| 1132 |
+
|
| 1133 |
+
training_args = DPOConfig(
|
| 1134 |
+
loss_type=["sigmoid", "bco_pair", "sft"], # ℒ = w_p·ℒ_p + w_q·ℒ_q + w_g·ℒ_g (Section 3.2 of the paper)
|
| 1135 |
+
loss_weights=[0.8, 0.2, 1.0], # w_p, w_q, w_g loss weights (Section 7 of the paper)
|
| 1136 |
+
learning_rate=5e-6, # learning rate (Section 7 of the paper)
|
| 1137 |
+
)
|
| 1138 |
+
```
|
| 1139 |
+
|
| 1140 |
+
## Kahneman–Tversky Optimization
|
| 1141 |
+
|
| 1142 |
+
Papers relating to the [`experimental.kto.KTOTrainer`]
|
| 1143 |
+
|
| 1144 |
+
### KTO: Model Alignment as Prospect Theoretic Optimization
|
| 1145 |
+
|
| 1146 |
+
**📜 Paper**: https://huggingface.co/papers/2402.01306
|
| 1147 |
+
|
| 1148 |
+
KTO derives an alignment objective from prospect theory and learns directly from **binary** human feedback (liked/disliked), matching or surpassing DPO-style methods while handling imbalanced/noisy signals well.
|
| 1149 |
+
To reproduce the paper's setting, you can use the default configuration of [`experimental.kto.KTOTrainer`]:
|
| 1150 |
+
|
| 1151 |
+
```python
|
| 1152 |
+
from trl.experimental.kto import KTOConfig, KTOTrainer
|
| 1153 |
+
from transformers import AutoModelForCausalLM, AutoTokenizer
|
| 1154 |
+
|
| 1155 |
+
model = AutoModelForCausalLM.from_pretrained(model_id)
|
| 1156 |
+
tokenizer = AutoTokenizer.from_pretrained(model_id)
|
| 1157 |
+
|
| 1158 |
+
trainer = KTOTrainer(
|
| 1159 |
+
model=model,
|
| 1160 |
+
processing_class=tokenizer,
|
| 1161 |
+
args=KTOConfig(),
|
| 1162 |
+
train_dataset=...,
|
| 1163 |
+
)
|
| 1164 |
+
trainer.train()
|
| 1165 |
+
```
|
| 1166 |
+
|
| 1167 |
+
## Supervised Fine-Tuning
|
| 1168 |
+
|
| 1169 |
+
Papers relating to the [`SFTTrainer`]
|
| 1170 |
+
|
| 1171 |
+
### EMA Without the Lag: Bias-Corrected Iterate Averaging Schemes
|
| 1172 |
+
|
| 1173 |
+
**📜 Paper**: https://huggingface.co/papers/2508.00180
|
| 1174 |
+
|
| 1175 |
+
Bias-Corrected Exponential Moving Average (BEMA) improves the stability and efficiency of language model fine-tuning by reducing stochasticity and eliminating bias. To use BEMA with SFT as described in the paper, you can use the [`BEMACallback`]:
|
| 1176 |
+
|
| 1177 |
+
```python
|
| 1178 |
+
from trl import BEMACallback, SFTTrainer
|
| 1179 |
+
|
| 1180 |
+
trainer = SFTTrainer(
|
| 1181 |
+
...
|
| 1182 |
+
callbacks=[BEMACallback()],
|
| 1183 |
+
)
|
| 1184 |
+
```
|
| 1185 |
+
|
| 1186 |
+
### On the Generalization of SFT: A Reinforcement Learning Perspective with Reward Rectification
|
| 1187 |
+
|
| 1188 |
+
**📜 Paper**: https://huggingface.co/papers/2508.05629
|
| 1189 |
+
|
| 1190 |
+
Dynamic Fine-Tuning (DFT) improves the generalization of Large Language Models (LLMs) by dynamically rescaling gradients, outperforming standard Supervised Fine-Tuning (SFT) and showing competitive results in offline reinforcement learning.
|
| 1191 |
+
|
| 1192 |
+
$$
|
| 1193 |
+
\mathcal{L}_{\text{DFT}}(\theta) = \mathbb{E}_{(x,y) \sim \mathcal{D}} \left[ - \sum_{t=1}^{|y|} \textcolor{red}{\text{sg}\big(\pi_\theta(y_t \mid y_{<t}, x)\big)} \; \log \pi_\theta(y_t \mid y_{<t}, x) \right]
|
| 1194 |
+
$$
|
| 1195 |
+
|
| 1196 |
+
where \\( \text{sg}(\cdot) \\) is the stop-gradient operator. To use DFT with SFT as described in the paper, you can use the `loss_type="dft"` argument:
|
| 1197 |
+
|
| 1198 |
+
```python
|
| 1199 |
+
from trl import SFTConfig
|
| 1200 |
+
|
| 1201 |
+
training_args = SFTConfig(
|
| 1202 |
+
loss_type="dft",
|
| 1203 |
+
...
|
| 1204 |
+
)
|
| 1205 |
+
```
|
| 1206 |
+
|
| 1207 |
+
To closely match the paper’s setup, you can use the following configuration (see Sec. 4.1). Authors also mention that the hyperparameters are not very sensitive (Sec. 4.3):
|
| 1208 |
+
|
| 1209 |
+
```python
|
| 1210 |
+
SFTConfig(
|
| 1211 |
+
loss_type="dft",
|
| 1212 |
+
learning_rate=5e-5,
|
| 1213 |
+
max_length=2048,
|
| 1214 |
+
# Target batch size 256; achieved via per-device batch 8 * grad accumulation 32
|
| 1215 |
+
per_device_train_batch_size=8,
|
| 1216 |
+
gradient_accumulation_steps=32,
|
| 1217 |
+
)
|
| 1218 |
+
```
|
| 1219 |
+
|
| 1220 |
+
### Fewer Truncations Improve Language Modeling
|
| 1221 |
+
|
| 1222 |
+
**📜 Paper**: https://huggingface.co/papers/2404.10830
|
| 1223 |
+
|
| 1224 |
+
The paper shows that the standard concatenate-then-split preprocessing (`packing_strategy="wrapped"`) used for LLM training causes many documents to be arbitrarily truncated, which harms learning. It proposes packing document chunks into context windows using a Best-Fit Decreasing bin-packing algorithm, greatly reducing truncation while keeping high token utilization and improving model performance. TRL implements this as the `"bfd_split"` packing strategy in [`SFTConfig`]. For more details on packing, see the [SFT documentation](sft_trainer#packing).
|
| 1225 |
+
|
| 1226 |
+
```python
|
| 1227 |
+
from trl import SFTConfig
|
| 1228 |
+
|
| 1229 |
+
training_args = SFTConfig(
|
| 1230 |
+
packing=True,
|
| 1231 |
+
packing_strategy="bfd_split",
|
| 1232 |
+
max_length=4096,
|
| 1233 |
+
)
|
| 1234 |
+
```
|
| 1235 |
+
|
| 1236 |
+
### Exploring the Limits of Transfer Learning with a Unified Text-to-Text Transformer
|
| 1237 |
+
|
| 1238 |
+
**📜 Paper**: https://huggingface.co/papers/1910.10683
|
| 1239 |
+
|
| 1240 |
+
The T5 paper proposes a unified text-to-text framework for transfer learning and introduces **sequence packing** (Section 3.5.2): grouping multiple short sequences into fixed-length blocks to reduce padding and improve training efficiency. Packing is supported in TRL via [`SFTConfig`] with the [`SFTTrainer`]. To enable packing with TRL, use this configuration:
|
| 1241 |
+
|
| 1242 |
+
```python
|
| 1243 |
+
from trl import SFTConfig
|
| 1244 |
+
|
| 1245 |
+
training_args = SFTConfig(
|
| 1246 |
+
packing=True, # enable sequence packing (Section 3.5.2 of the paper)
|
| 1247 |
+
max_length=512, # packed sequence length (Section 3.5.2 of the paper)
|
| 1248 |
+
)
|
| 1249 |
+
```
|
| 1250 |
+
|
| 1251 |
+
## Parameter-Efficient Fine-Tuning (PEFT)
|
| 1252 |
+
|
| 1253 |
+
For general details on using PEFT with TRL, please refer to the [PEFT Integration](peft_integration) guide.
|
| 1254 |
+
|
| 1255 |
+
### LoRA: Low-Rank Adaptation of Large Language Models
|
| 1256 |
+
|
| 1257 |
+
**📜 Paper**: https://huggingface.co/papers/2106.09685
|
| 1258 |
+
|
| 1259 |
+
Low-Rank Adaptation (LoRA) reduces the number of trainable parameters and GPU memory usage in large-scale pre-trained models while maintaining or improving performance on downstream tasks. TRL integrates LoRA via the [PEFT library](https://huggingface.co/docs/peft/index) and can be easily enabled in any TRL trainer by passing a [`~peft.LoraConfig`] to the `peft_config` argument. Here is an example of using LoRA with the [`SFTTrainer`]:
|
| 1260 |
+
|
| 1261 |
+
```python
|
| 1262 |
+
from trl import SFTTrainer
|
| 1263 |
+
from peft import LoraConfig
|
| 1264 |
+
|
| 1265 |
+
trainer = SFTTrainer(
|
| 1266 |
+
...,
|
| 1267 |
+
peft_config=LoraConfig(),
|
| 1268 |
+
)
|
| 1269 |
+
```
|
| 1270 |
+
|
| 1271 |
+
### DoRA: Weight-Decomposed Low-Rank Adaptation
|
| 1272 |
+
|
| 1273 |
+
**📜 Paper**: https://huggingface.co/papers/2402.09353
|
| 1274 |
+
|
| 1275 |
+
Weight-Decomposed Low-Rank Adaptation (DoRA) can improve the performance of LoRA, especially at low ranks. DoRA decomposes pre-trained weight into two component: magnitude and direction. Direction is handled by normal LoRA, and magnitude is learnable parameters. TRL integrate DoRA via the [PEFT library](https://huggingface.co/docs/peft/index) and can be easily enable through setting `use_dora=True` to the [`~peft.LoraConfig`].
|
| 1276 |
+
|
| 1277 |
+
``` python
|
| 1278 |
+
from peft import LoraConfig
|
| 1279 |
+
|
| 1280 |
+
config = LoraConfig(use_dora=True, ...)
|
| 1281 |
+
```
|
| 1282 |
+
|
| 1283 |
+
## Reinforce Leave-One-Out
|
| 1284 |
+
|
| 1285 |
+
Papers relating to the [`RLOOTrainer`]
|
| 1286 |
+
|
| 1287 |
+
### Back to Basics: Revisiting REINFORCE Style Optimization for Learning from Human Feedback in LLMs
|
| 1288 |
+
|
| 1289 |
+
**📜 Paper**: https://huggingface.co/papers/2402.14740
|
| 1290 |
+
|
| 1291 |
+
RLOO is a variant of REINFORCE that reduces variance by using leave-one-out baselines. It computes rewards by comparing each sample against the average of all other samples in the batch, providing more stable gradients than standard REINFORCE. To reproduce the paper's setting, use this configuration:
|
| 1292 |
+
|
| 1293 |
+
```python
|
| 1294 |
+
from trl import RLOOConfig
|
| 1295 |
+
|
| 1296 |
+
training_args = RLOOConfig(
|
| 1297 |
+
per_device_train_batch_size=512, # section C Training Detail of the paper
|
| 1298 |
+
steps_per_generation=2 # section C Training Detail of the paper
|
| 1299 |
+
beta=0.03 # section C Training Detail of the paper
|
| 1300 |
+
num_generations=2, # experiments of paper different num_generations={2,4}
|
| 1301 |
+
learning_rate=1e-6 # section C Training Detail of the paper
|
| 1302 |
+
)
|
| 1303 |
+
```
|
| 1304 |
+
|
| 1305 |
+
### REINFORCE++: A Simple and Efficient Approach for Aligning Large Language Models
|
| 1306 |
+
|
| 1307 |
+
**📜 Paper**: https://huggingface.co/papers/2501.03262
|
| 1308 |
+
|
| 1309 |
+
REINFORCE++ is an enhanced variant of the classical REINFORCE algorithm that incorporates key optimization techniques from PPO while eliminating the need for a critic network. It achieves simplicity, enhanced training stability, and reduced computational overhead through global advantage normalization across the entire batch. To approximate the paper's setting with the [`RLOOTrainer`], use this configuration:
|
| 1310 |
+
|
| 1311 |
+
```python
|
| 1312 |
+
from trl import RLOOConfig
|
| 1313 |
+
|
| 1314 |
+
training_args = RLOOConfig(
|
| 1315 |
+
normalize_advantages=True, # global advantage normalization, core of REINFORCE++
|
| 1316 |
+
)
|
| 1317 |
+
```
|
| 1318 |
+
|
| 1319 |
+
## Odds Ratio Preference Optimization
|
| 1320 |
+
|
| 1321 |
+
Papers relating to the [`experimental.orpo.ORPOTrainer`]
|
| 1322 |
+
|
| 1323 |
+
### ORPO: Monolithic Preference Optimization without Reference Model
|
| 1324 |
+
|
| 1325 |
+
**📜 Paper**: https://huggingface.co/papers/2403.07691
|
| 1326 |
+
|
| 1327 |
+
The introduction of a reference model-free monolithic odds ratio preference optimization algorithm (ORPO) enhances preference alignment during supervised fine-tuning, surpassing larger models in key evaluations. To reproduce the paper's setting, use this configuration:
|
| 1328 |
+
|
| 1329 |
+
```python
|
| 1330 |
+
from trl.experimental.orpo import ORPOConfig
|
| 1331 |
+
|
| 1332 |
+
training_args = ORPOConfig(
|
| 1333 |
+
beta=0.1, # λ odds ratio loss weight (Table 7 of the paper, Mistral-ORPO-β)
|
| 1334 |
+
learning_rate=5e-6, # learning rate (Appendix C of the paper)
|
| 1335 |
+
lr_scheduler_type="inverse_sqrt", # scheduler (Appendix C of the paper)
|
| 1336 |
+
num_train_epochs=5, # Appendix C of the paper
|
| 1337 |
+
warmup_steps=200, # warm-up steps (Appendix C of the paper)
|
| 1338 |
+
per_device_train_batch_size=8, # batch size (Appendix C of the paper)
|
| 1339 |
+
)
|
| 1340 |
+
```
|
| 1341 |
+
|
| 1342 |
+
## Contrastive Preference Optimization
|
| 1343 |
+
|
| 1344 |
+
Papers relating to the [`experimental.cpo.CPOTrainer`]
|
| 1345 |
+
|
| 1346 |
+
### Contrastive Preference Optimization: Pushing the Boundaries of LLM Performance in Machine Translation
|
| 1347 |
+
|
| 1348 |
+
**📜 Paper**: https://huggingface.co/papers/2401.08417
|
| 1349 |
+
|
| 1350 |
+
Introduces Contrastive Preference Optimization (CPO), a preference-based method for machine translation that trains models to avoid adequate-but-imperfect translations instead of mimicking references as in SFT. The paper analyzes limitations of SFT on MT (including reference quality issues) and shows that applying CPO to ALMA with only 22K parallel sentences yields ALMA-R, which matches or exceeds WMT competition winners and GPT-4 on WMT'21–WMT'23. Used in TRL via [`experimental.cpo.CPOTrainer`]. To reproduce the paper's setting, use this configuration:
|
| 1351 |
+
|
| 1352 |
+
```python
|
| 1353 |
+
from trl.experimental.cpo import CPOConfig
|
| 1354 |
+
|
| 1355 |
+
training_args = CPOConfig(
|
| 1356 |
+
loss_type="sigmoid", # preference learning loss (Section 3 of the paper)
|
| 1357 |
+
cpo_alpha=1.0, # NLL regularizer weight (Section 3 of the paper)
|
| 1358 |
+
beta=0.1, # β temperature (Section 4.2 of the paper)
|
| 1359 |
+
learning_rate=1e-4, # learning rate (official code)
|
| 1360 |
+
lr_scheduler_type="inverse_sqrt", # scheduler (official code)
|
| 1361 |
+
num_train_epochs=1, # Section 4.2 of the paper
|
| 1362 |
+
warmup_ratio=0.01, # warm-up ratio (Section 4.2 of the paper)
|
| 1363 |
+
max_length=512, # max sequence length (Section 4.2 of the paper)
|
| 1364 |
+
)
|
| 1365 |
+
```
|
| 1366 |
+
|
| 1367 |
+
### SimPO: Simple Preference Optimization with a Reference-Free Reward
|
| 1368 |
+
|
| 1369 |
+
**📜 Paper**: https://huggingface.co/papers/2405.14734
|
| 1370 |
+
|
| 1371 |
+
SimPO is a simpler yet more effective preference optimization approach that uses the average log probability of a sequence as the implicit reward, eliminating the need for a reference model. It introduces a target reward margin to the Bradley-Terry objective to encourage a larger margin between winning and losing responses. To reproduce the paper's setting, use this configuration:
|
| 1372 |
+
|
| 1373 |
+
```python
|
| 1374 |
+
from trl.experimental.cpo import CPOConfig
|
| 1375 |
+
|
| 1376 |
+
training_args = CPOConfig(
|
| 1377 |
+
loss_type="simpo", # SimPO loss (Section 3 of the paper)
|
| 1378 |
+
cpo_alpha=0.0, # no BC regularizer for SimPO
|
| 1379 |
+
beta=2.5, # β in Appendix B of the paper
|
| 1380 |
+
simpo_gamma=1.375, # γ target reward margin, from γ/β=0.55 in Appendix B of the paper
|
| 1381 |
+
learning_rate=1e-6, # learning rate in Appendix B of the paper
|
| 1382 |
+
num_train_epochs=1, # Appendix B of the paper
|
| 1383 |
+
)
|
| 1384 |
+
```
|
| 1385 |
+
|
| 1386 |
+
### AlphaPO -- Reward shape matters for LLM alignment
|
| 1387 |
+
|
| 1388 |
+
**📜 Paper**: https://huggingface.co/papers/2501.03884
|
| 1389 |
+
|
| 1390 |
+
AlphaPO is a new Direct Alignment Algorithms (DAAs) method that leverages an alpha-parameter to help change the shape of the reward function beyond the standard log reward. AlphaPO helps maintain fine-grained control over likelihood displacement and over-optimization. To reproduce the paper's setting, use this configuration:
|
| 1391 |
+
|
| 1392 |
+
```python
|
| 1393 |
+
from trl.experimental.cpo import CPOConfig
|
| 1394 |
+
|
| 1395 |
+
# Mistral-Instruct from Table 3 of the paper
|
| 1396 |
+
training_args = CPOConfig(
|
| 1397 |
+
loss_type="alphapo",
|
| 1398 |
+
alpha=0.25,
|
| 1399 |
+
beta=2.5,
|
| 1400 |
+
simpo_gamma=0.1,
|
| 1401 |
+
learning_rate=7e-7,
|
| 1402 |
+
...
|
| 1403 |
+
)
|
| 1404 |
+
```
|
| 1405 |
+
|
| 1406 |
+
## Triple Preference Optimization
|
| 1407 |
+
|
| 1408 |
+
Papers relating to the [`experimental.tpo.TPOTrainer`]
|
| 1409 |
+
|
| 1410 |
+
### Triple Preference Optimization: Achieving Better Alignment using a Single Step Optimization
|
| 1411 |
+
|
| 1412 |
+
**📜 Paper**: https://huggingface.co/papers/2405.16681
|
| 1413 |
+
|
| 1414 |
+
Introduces Triple Preference Optimization (TPO), a preference learning method that aligns an LLM with three responses per prompt — a gold (`reference`) completion, a preferred (`chosen`) completion and a dispreferred (`rejected`) completion — in a single optimization step. TPO combines a contrastive objective on the (chosen, rejected) pair with a supervised NLL term on the gold response, removing the need for a separate SFT stage and the reference model used in DPO. Used in TRL via [`experimental.tpo.TPOTrainer`]. To reproduce the paper's setting (Llama-3-Base, 5K), use this configuration:
|
| 1415 |
+
|
| 1416 |
+
```python
|
| 1417 |
+
from trl.experimental.tpo import TPOConfig
|
| 1418 |
+
|
| 1419 |
+
training_args = TPOConfig(
|
| 1420 |
+
loss_type="sigmoid", # contrastive loss between chosen and rejected (Section 3 of the paper)
|
| 1421 |
+
tpo_alpha=1.0, # weight of the NLL term on the gold response (Section 3 of the paper)
|
| 1422 |
+
beta=0.01, # β temperature (Table 6 of the paper)
|
| 1423 |
+
learning_rate=5e-7, # Table 6 of the paper
|
| 1424 |
+
num_train_epochs=1,
|
| 1425 |
+
max_length=1024,
|
| 1426 |
+
)
|
| 1427 |
+
```
|
| 1428 |
+
|
| 1429 |
+
To use the TPO-L variant (length-normalized log-probabilities with a target reward margin γ), set `loss_type="tpo-l"` and `tpo_l_gamma`:
|
| 1430 |
+
|
| 1431 |
+
```python
|
| 1432 |
+
from trl.experimental.tpo import TPOConfig
|
| 1433 |
+
|
| 1434 |
+
training_args = TPOConfig(
|
| 1435 |
+
loss_type="tpo-l", # length-normalized variant (Section 3 of the paper)
|
| 1436 |
+
tpo_alpha=1.0,
|
| 1437 |
+
beta=0.01,
|
| 1438 |
+
tpo_l_gamma=0.5, # γ target reward margin (Table 6 of the paper, Llama-3-Base 5K)
|
| 1439 |
+
learning_rate=5e-7,
|
| 1440 |
+
num_train_epochs=1,
|
| 1441 |
+
)
|
| 1442 |
+
```
|
| 1443 |
+
|
| 1444 |
+
## Nash Learning from Human Feedback
|
| 1445 |
+
|
| 1446 |
+
Papers relating to the [`experimental.nash_md.NashMDTrainer`]
|
| 1447 |
+
|
| 1448 |
+
### Nash Learning from Human Feedback
|
| 1449 |
+
|
| 1450 |
+
**📜 Paper**: https://huggingface.co/papers/2312.00886
|
| 1451 |
+
|
| 1452 |
+
Introduces Nash-MD, an alternative to standard RLHF that learns a preference model conditioned on two inputs and finds a policy at the Nash equilibrium. Instead of optimizing against a reward model, Nash-MD produces policies that consistently generate responses preferred over those of any competing policy. The algorithm is based on mirror descent principles. Used in TRL via [`experimental.nash_md.NashMDTrainer`].
|
| 1453 |
+
|
| 1454 |
+
```python
|
| 1455 |
+
from trl.experimental.nash_md import NashMDConfig, NashMDTrainer
|
| 1456 |
+
from transformers import AutoModelForCausalLM, AutoModelForSequenceClassification, AutoTokenizer
|
| 1457 |
+
|
| 1458 |
+
model = AutoModelForCausalLM.from_pretrained(model_id)
|
| 1459 |
+
tokenizer = AutoTokenizer.from_pretrained(model_id)
|
| 1460 |
+
reward_model = AutoModelForSequenceClassification.from_pretrained(reward_model_id, num_labels=1)
|
| 1461 |
+
|
| 1462 |
+
trainer = NashMDTrainer(
|
| 1463 |
+
model=model,
|
| 1464 |
+
reward_funcs=reward_model,
|
| 1465 |
+
args=NashMDConfig(),
|
| 1466 |
+
processing_class=tokenizer,
|
| 1467 |
+
train_dataset=...,
|
| 1468 |
+
)
|
| 1469 |
+
trainer.train()
|
| 1470 |
+
```
|
| 1471 |
+
|
| 1472 |
+
## Reward Modeling
|
| 1473 |
+
|
| 1474 |
+
Papers relating to the [`RewardTrainer`] and [`experimental.prm.PRMTrainer`]
|
| 1475 |
+
|
| 1476 |
+
### Solving math word problems with process- and outcome-based feedback
|
| 1477 |
+
|
| 1478 |
+
**📜 Paper**: https://huggingface.co/papers/2211.14275
|
| 1479 |
+
|
| 1480 |
+
Compares process-based supervision (per-step reasoning feedback) and outcome-based supervision (final-answer only) for math reasoning on GSM8K. Outcome-based training yields similar final-answer error with less labeling, but process-based supervision or learned process reward models (PRMs) are needed to reduce reasoning-step errors. The paper improves prior best from 16.8% to 12.7% final-answer error and 14.0% to 3.4% reasoning error among correct-answer solutions. Used in TRL via [`experimental.prm.PRMTrainer`]. To train a PRM using TRL, use this configuration:
|
| 1481 |
+
|
| 1482 |
+
```python
|
| 1483 |
+
from trl.experimental.prm import PRMConfig
|
| 1484 |
+
|
| 1485 |
+
training_args = PRMConfig(
|
| 1486 |
+
step_separator="\n", # separator between reasoning steps (TRL implementation detail)
|
| 1487 |
+
train_on_last_step_only=False, # supervise all steps, not just the last one (TRL implementation detail)
|
| 1488 |
+
)
|
| 1489 |
+
```
|
| 1490 |
+
|
| 1491 |
+
The paper does not specify training hyperparameters; it focuses on comparing process-based vs outcome-based supervision strategies.
|
| 1492 |
+
|
| 1493 |
+
### Helping or Herding? Reward Model Ensembles Mitigate but do not Eliminate Reward Hacking
|
| 1494 |
+
|
| 1495 |
+
**📜 Paper**: https://huggingface.co/papers/2312.09244
|
| 1496 |
+
|
| 1497 |
+
This paper proposed an auxiliary loss function designed to directly learn a centered reward model. This auxiliary loss minimizes the squared sum of the rewards, encouraging the model to naturally produce mean-zero outputs and thereby resolving the issue of underdetermination.
|
| 1498 |
+
|
| 1499 |
+
$$
|
| 1500 |
+
\mathcal{L}(\theta) = - \mathbb{E}_{(x,y^+,y^-) \sim \mathcal{D}} \left[ \log \sigma(r_\theta(x, y^+) - r_\theta(x, y^-)) \textcolor{red}{- \eta \cdot (r_\theta(x, y^+) + r_\theta(x, y^-))^2} \right].
|
| 1501 |
+
$$
|
| 1502 |
+
|
| 1503 |
+
To use this auxiliary loss with [`RewardTrainer`], you can use the `center_rewards_coefficient` argument in [`RewardConfig`] as follows:
|
| 1504 |
+
|
| 1505 |
+
```python
|
| 1506 |
+
from trl import RewardConfig
|
| 1507 |
+
|
| 1508 |
+
training_args = RewardConfig(
|
| 1509 |
+
center_rewards_coefficient=0.01, # η in the paper
|
| 1510 |
+
...
|
| 1511 |
+
)
|
| 1512 |
+
```
|
| 1513 |
+
|
| 1514 |
+
### Llama 2: Open Foundation and Fine-Tuned Chat Models
|
| 1515 |
+
|
| 1516 |
+
**📜 Paper**: https://huggingface.co/papers/2307.09288
|
| 1517 |
+
|
| 1518 |
+
In this paper, the authors propose to leverage their preference ratings being decomposed as a scale of four points (e.g., _significantly better_) to provide more informative feedback to the reward model. This is done by adding a margin to the loss function, which encourages the reward model to assign larger gaps in scores for pairs with higher preference ratings.
|
| 1519 |
+
|
| 1520 |
+
$$
|
| 1521 |
+
\mathcal{L}(\theta) = - \mathbb{E}_{(x,y^+,y^-,\textcolor{red}{m}) \sim \mathcal{D}} \left[ \log \sigma(r_\theta(x, y^+) - r_\theta(x, y^-) \textcolor{red}{- m}) \right].
|
| 1522 |
+
$$
|
| 1523 |
+
|
| 1524 |
+
You can add a margin to the loss by adding a `margin` column to the dataset. The following example shows how to set up a the "Margin Small" setting of the paper.
|
| 1525 |
+
|
| 1526 |
+
```python
|
| 1527 |
+
def add_margin(example):
|
| 1528 |
+
preference_to_margin = {
|
| 1529 |
+
"significantly better": 1.0,
|
| 1530 |
+
"better": 2.0/3.0,
|
| 1531 |
+
"slightly better": 1.0/3.0,
|
| 1532 |
+
"negligibly better / unsure": 0.0,
|
| 1533 |
+
}
|
| 1534 |
+
return {"margin": preference_to_margin[example["preference_label"]]}
|
| 1535 |
+
|
| 1536 |
+
dataset = dataset.map(add_margin)
|
| 1537 |
+
```
|
| 1538 |
+
|
| 1539 |
+
## Online Direct Preference Optimization
|
| 1540 |
+
|
| 1541 |
+
Papers relating to the [`experimental.odpo.OnlineDPOTrainer`]
|
| 1542 |
+
|
| 1543 |
+
### Direct Language Model Alignment from Online AI Feedback
|
| 1544 |
+
|
| 1545 |
+
**📜 Paper**: https://huggingface.co/papers/2402.04792
|
| 1546 |
+
|
| 1547 |
+
Online DPO improves direct alignment from preferences methods by providing real-time feedback from a model, outperforming both DPO and PPO methods.
|
| 1548 |
+
|
| 1549 |
+
To use Online DPO, you can use the [`experimental.odpo.OnlineDPOTrainer`].
|
| 1550 |
+
|
| 1551 |
+
### Exploratory Preference Optimization: Harnessing Implicit Q*-Approximation for Sample-Efficient RLHF
|
| 1552 |
+
|
| 1553 |
+
**📜 Paper**: https://huggingface.co/papers/2405.21046
|
| 1554 |
+
|
| 1555 |
+
XPO augments the DPO objective with a novel and principled exploration bonus, empowering the algorithm to explore outside the support of the initial model and human feedback data. It is a one-line change to online DPO that is provably sample-efficient and converges to a near-optimal language model policy. The paper defines α > 0 (optimism coefficient) and β > 0 (KL regularization) in Algorithm 1 but does not specify numerical values. The following configuration uses TRL defaults:
|
| 1556 |
+
|
| 1557 |
+
```python
|
| 1558 |
+
from trl.experimental.xpo import XPOConfig
|
| 1559 |
+
|
| 1560 |
+
training_args = XPOConfig(
|
| 1561 |
+
alpha=1e-5, # α exploration bonus weight, α ≥ 0 where α=0 reduces to online DPO (TRL default)
|
| 1562 |
+
beta=0.1, # β KL regularization coefficient (TRL default)
|
| 1563 |
+
)
|
| 1564 |
+
```
|
| 1565 |
+
|
| 1566 |
+
## Distillation
|
| 1567 |
+
|
| 1568 |
+
Papers relating to training a student model with the help of a teacher model.
|
| 1569 |
+
|
| 1570 |
+
### On-Policy Distillation of Language Models: Learning from Self-Generated Mistakes
|
| 1571 |
+
|
| 1572 |
+
**📜 Paper**: https://huggingface.co/papers/2306.13649
|
| 1573 |
+
|
| 1574 |
+
Introduces Generalized Knowledge Distillation (GKD), which addresses distribution mismatch in KD for auto-regressive models by training the student on its own generated outputs with teacher feedback, instead of a fixed set of sequences. GKD supports flexible loss functions (e.g. beyond KL when the student cannot match the teacher) and integrates with RL fine-tuning (RLHF). The paper reports results on summarization, translation, arithmetic reasoning, and instruction-tuning. Used in TRL via [`experimental.distillation.DistillationTrainer`] and [`experimental.gkd.GKDTrainer`]. To reproduce the paper's setting, use this configuration:
|
| 1575 |
+
|
| 1576 |
+
```python
|
| 1577 |
+
from trl.experimental.distillation import DistillationConfig
|
| 1578 |
+
|
| 1579 |
+
# XSum summarization task (Table A.1 of the paper)
|
| 1580 |
+
training_args = DistillationConfig(
|
| 1581 |
+
lmbda=0.5, # λ student data fraction (Section 3 of the paper)
|
| 1582 |
+
beta=0.5, # β Generalized JSD interpolation, 0=KL, 1=reverse KL (Section 3 of the paper)
|
| 1583 |
+
temperature=1.0, # student training temperature (Appendix A of the paper)
|
| 1584 |
+
max_steps=40000, # training steps (Table A.1 of the paper)
|
| 1585 |
+
learning_rate=3e-4, # learning rate (Table A.1 of the paper)
|
| 1586 |
+
per_device_train_batch_size=32, # batch size (Table A.1 of the paper)
|
| 1587 |
+
warmup_steps=2000, # warm-up steps (Table A.1 of the paper)
|
| 1588 |
+
max_completion_length=64, # max output tokens (Table A.1 of the paper)
|
| 1589 |
+
)
|
| 1590 |
+
```
|
| 1591 |
+
|
| 1592 |
+
### On-Policy Distillation
|
| 1593 |
+
|
| 1594 |
+
**📰 Blog**: https://thinkingmachines.ai/blog/on-policy-distillation/
|
| 1595 |
+
|
| 1596 |
+
On-Policy Distillation involves a student model generating rollouts for each batch of training data. We subsequently obtain the probability distributions for each token of the rollouts from both the student and teacher models. The student model is then optimized to minimize the negative Kullback-Leibler (KL) divergence between its own token distributions and those of the teacher model.
|
| 1597 |
+
|
| 1598 |
+
| Method | Sampling | Reward signal |
|
| 1599 |
+
|-------------------------|------------|---------------|
|
| 1600 |
+
| Supervised finetuning | off-policy | dense |
|
| 1601 |
+
| Reinforcement learning | on-policy | sparse |
|
| 1602 |
+
| On-policy distillation | on-policy | dense |
|
| 1603 |
+
|
| 1604 |
+
On-Policy Distillation has been shown to outperform SFT, GRPO and can be used to restore generalization capabilities lost during SFT.
|
| 1605 |
+
|
| 1606 |
+
Additionally on-policy distillation is more compute efficient and is less prone to overfitting when trained with limited data.
|
| 1607 |
+
|
| 1608 |
+
To train a model with on-policy distillation using TRL, you can use the following configuration, with the [`experimental.distillation.DistillationTrainer`] and [`experimental.distillation.DistillationConfig`]:
|
| 1609 |
+
|
| 1610 |
+
```python
|
| 1611 |
+
from trl.experimental.distillation import DistillationConfig
|
| 1612 |
+
|
| 1613 |
+
training_args = DistillationConfig(
|
| 1614 |
+
lmbda=1.0, # student produces rollouts for all batches
|
| 1615 |
+
beta=1.0, # to ensure reverse-kl as the loss function
|
| 1616 |
+
teacher_model_name_or_path="teacher-model", # specify the teacher model
|
| 1617 |
+
)
|
| 1618 |
+
```
|
| 1619 |
+
|
| 1620 |
+
Alternatively, you can use the [`experimental.gkd.GKDTrainer`] and [`experimental.gkd.GKDConfig`]:
|
| 1621 |
+
|
| 1622 |
+
```python
|
| 1623 |
+
from trl.experimental.gkd import GKDConfig
|
| 1624 |
+
|
| 1625 |
+
training_args = GKDConfig(
|
| 1626 |
+
lmbda=1.0, # student produces rollouts for all batches
|
| 1627 |
+
beta=1.0, # to ensure reverse-kl as the loss function
|
| 1628 |
+
teacher_model_name_or_path="teacher-model", # specify the teacher model
|
| 1629 |
+
)
|
| 1630 |
+
```
|
| 1631 |
+
|
| 1632 |
+
You can also use the [`GOLDTrainer`] and [`GOLDConfig`] to perform on-policy distillation with a similar configuration:
|
| 1633 |
+
|
| 1634 |
+
```python
|
| 1635 |
+
from trl.experimental import GOLDConfig
|
| 1636 |
+
|
| 1637 |
+
config = GOLDConfig(
|
| 1638 |
+
lmbda=1.0, # student produces rollouts for all batches
|
| 1639 |
+
beta=1.0, # to ensure reverse-kl as the loss function
|
| 1640 |
+
teacher_model_name_or_path="teacher-model", # specify the teacher model
|
| 1641 |
+
|
| 1642 |
+
)
|
| 1643 |
+
```
|
| 1644 |
+
|
| 1645 |
+
### Knowledge Distillation of Large Language Models
|
| 1646 |
+
|
| 1647 |
+
**📜 Paper**: https://huggingface.co/papers/2306.08543
|
| 1648 |
+
|
| 1649 |
+
MiniLLM is the first on-policy knowledge distillation method, which minimizes the sequence-level reverse KLD between the teacher and the student model and is optimized by reinforcement learning.
|
| 1650 |
+
|
| 1651 |
+
It is a generalized version of [Think Machine Lab's On-Policy Distillation](https://thinkingmachines.ai/blog/on-policy-distillation/), with the option to add distribution-level single-step distillation signals (like GKD when `beta=1`) and long-context reverse KLD signals.
|
| 1652 |
+
|
| 1653 |
+
Alternatively, you can use the [`experimental.MiniLLMTrainer`] and [`experimental.MiniLLMConfig`] to perform MiniLLM distillation as follows:
|
| 1654 |
+
|
| 1655 |
+
```python
|
| 1656 |
+
from datasets import load_dataset
|
| 1657 |
+
from trl.experimental.minillm import MiniLLMTrainer
|
| 1658 |
+
|
| 1659 |
+
dataset = load_dataset("trl-lib/tldr", split="train")
|
| 1660 |
+
|
| 1661 |
+
trainer = MiniLLMTrainer(
|
| 1662 |
+
model="Qwen/Qwen3-0.6B",
|
| 1663 |
+
teacher_model="Qwen/Qwen3-1.7B",
|
| 1664 |
+
train_dataset=dataset,
|
| 1665 |
+
)
|
| 1666 |
+
trainer.train()
|
| 1667 |
+
```
|
| 1668 |
+
|
| 1669 |
+
For more details, see the [MiniLLM Trainer documentation](minillm) documentation.
|
| 1670 |
+
|
| 1671 |
+
### Reinforcement Learning via Self-Distillation
|
| 1672 |
+
|
| 1673 |
+
**📜 Paper**: https://huggingface.co/papers/2601.20802
|
| 1674 |
+
|
| 1675 |
+
Self-Distillation Policy Optimization (SDPO) enhances reinforcement learning with verifiable rewards by converting rich textual feedback (e.g., runtime errors, judge evaluations) into a dense learning signal without any external teacher or explicit reward model. SDPO treats the current model conditioned on feedback as a self-teacher and distills its feedback-informed next-token predictions back into the policy. Notably, SDPO also outperforms baselines in standard RLVR environments that only return scalar feedback by using successful rollouts as implicit feedback for failed attempts.
|
| 1676 |
+
|
| 1677 |
+
```python
|
| 1678 |
+
from trl.experimental.sdpo import SDPOConfig, SDPOTrainer
|
| 1679 |
+
|
| 1680 |
+
training_args = SDPOConfig(
|
| 1681 |
+
distillation_alpha=0.5, # Jensen-Shannon divergence (recommended)
|
| 1682 |
+
distillation_topk=100, # Top-K logit distillation approximation
|
| 1683 |
+
full_logit_distillation=True, # Required for top-K logit-level SDPO
|
| 1684 |
+
distillation_is_clip=2.0, # Importance sampling clipping
|
| 1685 |
+
distillation_weight=1.0, # Weight for self-distillation loss
|
| 1686 |
+
sdpo_policy_loss_mode="distillation_only",
|
| 1687 |
+
use_successful_as_teacher=True, # Use successful rollouts as teacher
|
| 1688 |
+
teacher_regularization="ema", # Supported: "ema", "none"
|
| 1689 |
+
teacher_update_rate=0.05, # EMA update rate
|
| 1690 |
+
include_environment_feedback=False, # Use dataset privileged_context when available
|
| 1691 |
+
)
|
| 1692 |
+
|
| 1693 |
+
trainer = SDPOTrainer(
|
| 1694 |
+
model="Qwen/Qwen2.5-1.5B-Instruct",
|
| 1695 |
+
reward_funcs=...,
|
| 1696 |
+
args=training_args,
|
| 1697 |
+
train_dataset=...,
|
| 1698 |
+
)
|
| 1699 |
+
trainer.train()
|
| 1700 |
+
```
|
| 1701 |
+
|
| 1702 |
+
Expected dataset columns:
|
| 1703 |
+
|
| 1704 |
+
- `prompt`
|
| 1705 |
+
- `privileged_context` for optional environment feedback
|
| 1706 |
+
|
| 1707 |
+
For more details, see the [SDPO Trainer documentation](sdpo_trainer).
|
| 1708 |
+
|
| 1709 |
+
### Self-Training with On-Policy Self-Distillation for Language Model Alignment
|
| 1710 |
+
|
| 1711 |
+
**📜 Paper**: https://huggingface.co/papers/2601.19897
|
| 1712 |
+
|
| 1713 |
+
Self-Distilled Fine-Tuning (SDFT) performs on-policy self-distillation by generating completions during training, then distilling an explicit teacher-conditioned view of those same completions back into the student. In TRL, SDFT uses a shared self-distillation core with SDPO where the teacher is the model itself (base weights with adapter disabled for PEFT, or the same model under `no_grad` for non-PEFT).
|
| 1714 |
+
The teacher prompt is composed internally from the student `prompt` plus the dataset `privileged_context`.
|
| 1715 |
+
|
| 1716 |
+
```python
|
| 1717 |
+
from datasets import Dataset
|
| 1718 |
+
|
| 1719 |
+
from trl.experimental.sdft import SDFTConfig, SDFTTrainer
|
| 1720 |
+
|
| 1721 |
+
dataset = Dataset.from_dict(
|
| 1722 |
+
{
|
| 1723 |
+
"prompt": [[{"role": "user", "content": "Solve 2+2."}]],
|
| 1724 |
+
"privileged_context": ["Example answer: 4."],
|
| 1725 |
+
}
|
| 1726 |
+
)
|
| 1727 |
+
|
| 1728 |
+
training_args = SDFTConfig(
|
| 1729 |
+
distillation_alpha=0.5,
|
| 1730 |
+
distillation_topk=5,
|
| 1731 |
+
max_completion_length=64,
|
| 1732 |
+
)
|
| 1733 |
+
|
| 1734 |
+
trainer = SDFTTrainer(
|
| 1735 |
+
model="Qwen/Qwen2.5-1.5B-Instruct",
|
| 1736 |
+
args=training_args,
|
| 1737 |
+
train_dataset=dataset,
|
| 1738 |
+
)
|
| 1739 |
+
trainer.train()
|
| 1740 |
+
```
|
| 1741 |
+
|
| 1742 |
+
Expected dataset columns:
|
| 1743 |
+
|
| 1744 |
+
- `prompt`
|
| 1745 |
+
- `privileged_context` containing only the extra teacher-only information
|
| 1746 |
+
|
| 1747 |
+
For more details, see the [SDFT Trainer documentation](sdft_trainer).
|
| 1748 |
+
|
| 1749 |
+
### Embarrassingly Simple Self-Distillation Improves Code Generation
|
| 1750 |
+
|
| 1751 |
+
**📜 Paper**: https://huggingface.co/papers/2604.01193
|
| 1752 |
+
|
| 1753 |
+
Simple Self-Distillation (SSD) improves code generation by sampling completions from the model at a training-time temperature and truncation configuration, then fine-tuning on those raw, unverified samples with standard cross-entropy loss. No reward model, verifier, teacher model, or reinforcement learning is needed. SSD reshapes token distributions in a context-dependent way: suppressing distractor tails at "lock" positions (where syntax leaves little ambiguity) while preserving diversity at "fork" positions (where multiple valid continuations exist).
|
| 1754 |
+
|
| 1755 |
+
```python
|
| 1756 |
+
from trl.experimental.ssd import SSDConfig, SSDTrainer
|
| 1757 |
+
|
| 1758 |
+
training_args = SSDConfig(
|
| 1759 |
+
temperature=0.6, # Training-time sampling temperature (T_train)
|
| 1760 |
+
top_k=20, # Training-time top-k truncation
|
| 1761 |
+
top_p=0.95, # Training-time top-p truncation
|
| 1762 |
+
max_completion_length=65536,
|
| 1763 |
+
learning_rate=5e-6,
|
| 1764 |
+
)
|
| 1765 |
+
|
| 1766 |
+
trainer = SSDTrainer(
|
| 1767 |
+
model="Qwen/Qwen3-4B-Instruct",
|
| 1768 |
+
args=training_args,
|
| 1769 |
+
train_dataset=...,
|
| 1770 |
+
)
|
| 1771 |
+
trainer.train()
|
| 1772 |
+
```
|
| 1773 |
+
|
| 1774 |
+
Expected dataset columns:
|
| 1775 |
+
|
| 1776 |
+
- `prompt`
|
| 1777 |
+
|
| 1778 |
+
For more details, see the [SSD Trainer documentation](ssd_trainer).
|
| 1779 |
+
|
| 1780 |
+
## Distributed Training
|
| 1781 |
+
|
| 1782 |
+
### ZeRO: Memory Optimizations Toward Training Trillion Parameter Models
|
| 1783 |
+
|
| 1784 |
+
**📜 Paper**: https://huggingface.co/papers/1910.02054
|
| 1785 |
+
|
| 1786 |
+
ZeRO (Zero Redundancy Optimizer) eliminates memory redundancies in data- and model-parallel training by partitioning optimizer states, gradients, and parameters across devices while retaining low communication volume and high computational granularity. This allows for the efficient training of large models that would otherwise not fit in GPU memory.
|
| 1787 |
+
|
| 1788 |
+
TRL supports ZeRO via the [DeepSpeed integration](deepspeed_integration). To use it, provide a DeepSpeed configuration file with your desired settings,
|
| 1789 |
+
|
| 1790 |
+
```yaml
|
| 1791 |
+
# config.yaml
|
| 1792 |
+
distributed_type: DEEPSPEED
|
| 1793 |
+
num_processes: 2
|
| 1794 |
+
deepspeed_config:
|
| 1795 |
+
zero_stage: 3
|
| 1796 |
+
```
|
| 1797 |
+
|
| 1798 |
+
and launch the training script using `accelerate launch --config_file config_file`.
|
| 1799 |
+
|
| 1800 |
+
```sh
|
| 1801 |
+
accelerate launch --config_file config.yaml train.py
|
| 1802 |
+
```
|
| 1803 |
+
|
| 1804 |
+
## Proximal Policy Optimization
|
| 1805 |
+
|
| 1806 |
+
Papers relating to the [`experimental.ppo.PPOTrainer`]
|
| 1807 |
+
|
| 1808 |
+
### Proximal Policy Optimization Algorithms
|
| 1809 |
+
|
| 1810 |
+
**📜 Paper**: https://huggingface.co/papers/1707.06347
|
| 1811 |
+
|
| 1812 |
+
Introduces Proximal Policy Optimization (PPO): policy gradient methods that alternate between collecting rollouts and optimizing a clipped surrogate objective over multiple minibatch epochs. PPO retains benefits of trust-region methods (e.g. TRPO) with simpler implementation and strong empirical sample efficiency, and was validated on robotics and Atari benchmarks. Used in TRL via [`experimental.ppo.PPOTrainer`]. To use PPO with TRL, use this configuration:
|
| 1813 |
+
|
| 1814 |
+
```python
|
| 1815 |
+
from trl.experimental.ppo import PPOConfig
|
| 1816 |
+
|
| 1817 |
+
training_args = PPOConfig(
|
| 1818 |
+
cliprange=0.2, # ε clipping range (Section 3 and Table 3 of the paper, Mujoco setting)
|
| 1819 |
+
num_ppo_epochs=4, # K epochs of minibatch updates (TRL default; paper uses K=10 Mujoco, K=3 Atari)
|
| 1820 |
+
gamma=1.0, # γ discount factor (TRL default for LLM tasks; paper uses γ=0.99)
|
| 1821 |
+
lam=0.95, # λ GAE parameter (Table 3 of the paper, Mujoco setting)
|
| 1822 |
+
kl_coef=0.05, # KL penalty coefficient (Section 4 of the paper discusses adaptive KL)
|
| 1823 |
+
vf_coef=0.1, # c₁ value function loss weight (Equation 9 of the paper)
|
| 1824 |
+
)
|
| 1825 |
+
```
|
tasks/tasksmith-1c108f674e97/tests/source/docs/source/papo_trainer.md
ADDED
|
@@ -0,0 +1,20 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# PAPO Trainer
|
| 2 |
+
|
| 3 |
+
[](https://huggingface.co/models?other=papo,trl)
|
| 4 |
+
|
| 5 |
+
TRL supports the Perception-Aware Policy Optimization (PAPO) as described in the paper [Perception-Aware Policy Optimization for Multimodal Reasoning](https://huggingface.co/papers/2507.06448) by [Zhenhailong Wang](https://huggingface.co/mikewang), Xuehang Guo, Sofia Stoica, [Haiyang Xu](https://huggingface.co/xhyandwyy), Hongru Wang, Hyeonjeong Ha, Xiusi Chen, Yangyi Chen, Ming Yan, Fei Huang, Heng Ji
|
| 6 |
+
|
| 7 |
+
The abstract from the paper is the following:
|
| 8 |
+
|
| 9 |
+
> Reinforcement Learning with Verifiable Rewards (RLVR) has proven to be a highly effective strategy for endowing Large Language Models (LLMs) with robust multi-step reasoning abilities. However, its design and optimizations remain tailored to purely textual domains, resulting in suboptimal performance when applied to multimodal reasoning tasks. In particular, we observe that a major source of error in current multimodal reasoning lies in the perception of visual inputs. To address this bottleneck, we propose Perception-Aware Policy Optimization (PAPO), a simple yet effective extension of GRPO that encourages the model to learn to perceive while learning to reason, entirely from internal supervision signals. Notably, PAPO does not rely on additional data curation, external reward models, or proprietary models. Specifically, we introduce the Implicit Perception Loss in the form of a KL divergence term to the GRPO objective, which, despite its simplicity, yields significant overall improvements (4.4%) on diverse multimodal benchmarks. The improvements are more pronounced, approaching 8.0%, on tasks with high vision dependency. We also observe a substantial reduction (30.5%) in perception errors, indicating improved perceptual capabilities with PAPO. We conduct comprehensive analysis of PAPO and identify a unique loss hacking issue, which we rigorously analyze and mitigate through a Double Entropy Loss. Overall, our work introduces a deeper integration of perception-aware supervision into RLVR learning objectives and lays the groundwork for a new RL framework that encourages visually grounded reasoning. Project page: https://mikewangwzhl.github.io/PAPO.
|
| 10 |
+
|
| 11 |
+
## PAPOTrainer
|
| 12 |
+
|
| 13 |
+
[[autodoc]] experimental.papo.PAPOTrainer
|
| 14 |
+
- train
|
| 15 |
+
- save_model
|
| 16 |
+
- push_to_hub
|
| 17 |
+
|
| 18 |
+
## PAPOConfig
|
| 19 |
+
|
| 20 |
+
[[autodoc]] experimental.papo.PAPOConfig
|
tasks/tasksmith-1c108f674e97/tests/source/docs/source/peft_integration.md
ADDED
|
@@ -0,0 +1,822 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# PEFT Integration
|
| 2 |
+
|
| 3 |
+
TRL supports [PEFT](https://github.com/huggingface/peft) (Parameter-Efficient Fine-Tuning) methods for memory-efficient model training. PEFT enables fine-tuning large language models by training only a small number of additional parameters while keeping the base model frozen, significantly reducing computational costs and memory requirements.
|
| 4 |
+
|
| 5 |
+
This guide covers how to use PEFT with different TRL trainers, including LoRA, QLoRA, and prompt tuning techniques.
|
| 6 |
+
|
| 7 |
+
For a complete working example, see the [SFT with LoRA/QLoRA notebook](https://github.com/huggingface/trl/blob/main/examples/notebooks/sft_trl_lora_qlora.ipynb).
|
| 8 |
+
|
| 9 |
+
## Installation
|
| 10 |
+
|
| 11 |
+
To use PEFT with TRL, install the required dependencies:
|
| 12 |
+
|
| 13 |
+
```bash
|
| 14 |
+
pip install trl[peft]
|
| 15 |
+
```
|
| 16 |
+
|
| 17 |
+
For QLoRA support (4-bit and 8-bit quantization), also install:
|
| 18 |
+
|
| 19 |
+
```bash
|
| 20 |
+
pip install bitsandbytes
|
| 21 |
+
```
|
| 22 |
+
|
| 23 |
+
## Quick Start
|
| 24 |
+
|
| 25 |
+
All TRL trainers support PEFT through the `peft_config` argument. The simplest way to enable PEFT is by using the command-line interface with the `--use_peft` flag:
|
| 26 |
+
|
| 27 |
+
```bash
|
| 28 |
+
python trl/scripts/sft.py \
|
| 29 |
+
--model_name_or_path Qwen/Qwen2-0.5B \
|
| 30 |
+
--dataset_name trl-lib/Capybara \
|
| 31 |
+
--use_peft \
|
| 32 |
+
--lora_r 32 \
|
| 33 |
+
--lora_alpha 16 \
|
| 34 |
+
--output_dir Qwen2-0.5B-SFT-LoRA
|
| 35 |
+
```
|
| 36 |
+
|
| 37 |
+
Alternatively, you can pass a PEFT config directly in your Python code:
|
| 38 |
+
|
| 39 |
+
```python
|
| 40 |
+
from peft import LoraConfig
|
| 41 |
+
from trl import SFTTrainer
|
| 42 |
+
|
| 43 |
+
# Configure LoRA
|
| 44 |
+
peft_config = LoraConfig(
|
| 45 |
+
r=32,
|
| 46 |
+
lora_alpha=16,
|
| 47 |
+
lora_dropout=0.05,
|
| 48 |
+
bias="none",
|
| 49 |
+
task_type="CAUSAL_LM",
|
| 50 |
+
)
|
| 51 |
+
|
| 52 |
+
# Configure training - note the higher learning rate for LoRA (10x base rate)
|
| 53 |
+
training_args = SFTConfig(
|
| 54 |
+
learning_rate=2.0e-4, # 10x the base rate (2.0e-5) for LoRA
|
| 55 |
+
...
|
| 56 |
+
)
|
| 57 |
+
|
| 58 |
+
# Create trainer with PEFT
|
| 59 |
+
trainer = SFTTrainer(
|
| 60 |
+
model=model,
|
| 61 |
+
train_dataset=dataset,
|
| 62 |
+
peft_config=peft_config,
|
| 63 |
+
)
|
| 64 |
+
```
|
| 65 |
+
|
| 66 |
+
## Three Ways to Configure PEFT
|
| 67 |
+
|
| 68 |
+
TRL provides three different methods to configure PEFT, each suited for different use cases:
|
| 69 |
+
|
| 70 |
+
### 1. Using CLI Flags (Simplest)
|
| 71 |
+
|
| 72 |
+
The easiest way to enable PEFT is to use the `--use_peft` flag with the command-line interface. This method is ideal for quick experiments and standard configurations:
|
| 73 |
+
|
| 74 |
+
```bash
|
| 75 |
+
python trl/scripts/sft.py \
|
| 76 |
+
--model_name_or_path Qwen/Qwen2-0.5B \
|
| 77 |
+
--dataset_name trl-lib/Capybara \
|
| 78 |
+
--use_peft \
|
| 79 |
+
--lora_r 32 \
|
| 80 |
+
--lora_alpha 16 \
|
| 81 |
+
--lora_dropout 0.05 \
|
| 82 |
+
--output_dir Qwen2-0.5B-SFT-LoRA
|
| 83 |
+
```
|
| 84 |
+
|
| 85 |
+
**Pros**: Quick setup, no code required
|
| 86 |
+
|
| 87 |
+
**Cons**: Limited to LoRA, fewer customization options
|
| 88 |
+
|
| 89 |
+
### 2. Passing peft_config to Trainer (Recommended)
|
| 90 |
+
|
| 91 |
+
For more control, pass a PEFT configuration directly to the trainer. This is the recommended approach for most use cases:
|
| 92 |
+
|
| 93 |
+
```python
|
| 94 |
+
from peft import LoraConfig
|
| 95 |
+
from trl import SFTConfig, SFTTrainer
|
| 96 |
+
|
| 97 |
+
peft_config = LoraConfig(
|
| 98 |
+
r=32,
|
| 99 |
+
lora_alpha=16,
|
| 100 |
+
lora_dropout=0.05,
|
| 101 |
+
bias="none",
|
| 102 |
+
task_type="CAUSAL_LM",
|
| 103 |
+
target_modules=["q_proj", "v_proj", "k_proj", "o_proj"],
|
| 104 |
+
)
|
| 105 |
+
|
| 106 |
+
trainer = SFTTrainer(
|
| 107 |
+
model=model,
|
| 108 |
+
args=training_args,
|
| 109 |
+
train_dataset=dataset,
|
| 110 |
+
peft_config=peft_config, # Pass config here
|
| 111 |
+
)
|
| 112 |
+
```
|
| 113 |
+
|
| 114 |
+
**Pros**: Full control, supports all PEFT methods (LoRA, Prompt Tuning, etc.)
|
| 115 |
+
|
| 116 |
+
**Cons**: Requires Python code
|
| 117 |
+
|
| 118 |
+
### 3. Applying PEFT to Model Directly (Advanced)
|
| 119 |
+
|
| 120 |
+
For maximum flexibility, you can apply PEFT to your model before passing it to the trainer:
|
| 121 |
+
|
| 122 |
+
```python
|
| 123 |
+
from peft import LoraConfig, get_peft_model
|
| 124 |
+
from transformers import AutoModelForCausalLM
|
| 125 |
+
from trl import SFTConfig, SFTTrainer
|
| 126 |
+
|
| 127 |
+
# Load base model
|
| 128 |
+
model = AutoModelForCausalLM.from_pretrained("Qwen/Qwen2-0.5B")
|
| 129 |
+
|
| 130 |
+
# Apply PEFT configuration
|
| 131 |
+
peft_config = LoraConfig(
|
| 132 |
+
r=32,
|
| 133 |
+
lora_alpha=16,
|
| 134 |
+
lora_dropout=0.05,
|
| 135 |
+
bias="none",
|
| 136 |
+
task_type="CAUSAL_LM",
|
| 137 |
+
)
|
| 138 |
+
model = get_peft_model(model, peft_config)
|
| 139 |
+
|
| 140 |
+
# Pass PEFT-wrapped model to trainer
|
| 141 |
+
trainer = SFTTrainer(
|
| 142 |
+
model=model, # Already has PEFT applied
|
| 143 |
+
args=training_args,
|
| 144 |
+
train_dataset=dataset,
|
| 145 |
+
# Note: no peft_config needed here
|
| 146 |
+
)
|
| 147 |
+
```
|
| 148 |
+
|
| 149 |
+
**Pros**: Maximum control, useful for custom model architectures or complex setups
|
| 150 |
+
|
| 151 |
+
**Cons**: More verbose, requires understanding of PEFT internals
|
| 152 |
+
|
| 153 |
+
## Learning Rate Considerations
|
| 154 |
+
|
| 155 |
+
When using LoRA or other PEFT methods, you typically need to use a **higher learning rate** (approximately 10x) compared to full fine-tuning. This is because PEFT methods train only a small fraction of parameters, requiring a larger learning rate to achieve similar parameter updates.
|
| 156 |
+
|
| 157 |
+
**Recommended learning rates:**
|
| 158 |
+
|
| 159 |
+
| Trainer | Full Fine-Tuning | With LoRA (10x) |
|
| 160 |
+
|---------|------------------|-----------------|
|
| 161 |
+
| **SFT** | `2.0e-5` | `2.0e-4` |
|
| 162 |
+
| **DPO** | `5.0e-7` | `5.0e-6` |
|
| 163 |
+
| **GRPO** | `1.0e-6` | `1.0e-5` |
|
| 164 |
+
| **Prompt Tuning** | N/A | `1.0e-2` to `3.0e-2` |
|
| 165 |
+
|
| 166 |
+
> **Why 10x?** LoRA adapters have significantly fewer trainable parameters than the full model. A higher learning rate compensates for this reduced parameter count, ensuring effective training. For detailed explanation, see [this blog post](https://thinkingmachines.ai/blog/lora/).
|
| 167 |
+
|
| 168 |
+
For additional best practices on using LoRA effectively, refer to the [LoRA Without Regret](lora_without_regret) documentation.
|
| 169 |
+
|
| 170 |
+
## PEFT with Different Trainers
|
| 171 |
+
|
| 172 |
+
TRL's trainers support PEFT configurations for various training paradigms. Below are detailed examples for each major trainer.
|
| 173 |
+
|
| 174 |
+
<hfoptions id="trainer-type">
|
| 175 |
+
<hfoption id="sft">
|
| 176 |
+
|
| 177 |
+
### Supervised Fine-Tuning (SFT)
|
| 178 |
+
|
| 179 |
+
The `SFTTrainer` is used for supervised fine-tuning on instruction datasets.
|
| 180 |
+
|
| 181 |
+
#### With LoRA
|
| 182 |
+
|
| 183 |
+
```bash
|
| 184 |
+
python trl/scripts/sft.py \
|
| 185 |
+
--model_name_or_path Qwen/Qwen2-0.5B \
|
| 186 |
+
--dataset_name trl-lib/Capybara \
|
| 187 |
+
--learning_rate 2.0e-4 \
|
| 188 |
+
--num_train_epochs 1 \
|
| 189 |
+
--per_device_train_batch_size 2 \
|
| 190 |
+
--gradient_accumulation_steps 8 \
|
| 191 |
+
--use_peft \
|
| 192 |
+
--lora_r 32 \
|
| 193 |
+
--lora_alpha 16 \
|
| 194 |
+
--output_dir Qwen2-0.5B-SFT-LoRA
|
| 195 |
+
```
|
| 196 |
+
|
| 197 |
+
#### Python Example
|
| 198 |
+
|
| 199 |
+
```python
|
| 200 |
+
from peft import LoraConfig
|
| 201 |
+
from trl import SFTConfig, SFTTrainer
|
| 202 |
+
|
| 203 |
+
# Configure LoRA
|
| 204 |
+
peft_config = LoraConfig(
|
| 205 |
+
r=32,
|
| 206 |
+
lora_alpha=16,
|
| 207 |
+
lora_dropout=0.05,
|
| 208 |
+
bias="none",
|
| 209 |
+
task_type="CAUSAL_LM",
|
| 210 |
+
target_modules=["q_proj", "v_proj"], # optional: specify target modules
|
| 211 |
+
)
|
| 212 |
+
|
| 213 |
+
# Configure training with higher learning rate for LoRA
|
| 214 |
+
training_args = SFTConfig(
|
| 215 |
+
learning_rate=2.0e-4, # 10x the base rate for LoRA
|
| 216 |
+
...
|
| 217 |
+
)
|
| 218 |
+
|
| 219 |
+
# Create trainer with PEFT config
|
| 220 |
+
trainer = SFTTrainer(
|
| 221 |
+
model="Qwen/Qwen2-0.5B", # can pass model name or loaded model
|
| 222 |
+
args=training_args,
|
| 223 |
+
train_dataset=dataset,
|
| 224 |
+
peft_config=peft_config, # pass PEFT config here
|
| 225 |
+
)
|
| 226 |
+
trainer.train()
|
| 227 |
+
```
|
| 228 |
+
|
| 229 |
+
</hfoption>
|
| 230 |
+
<hfoption id="dpo">
|
| 231 |
+
|
| 232 |
+
### Direct Preference Optimization (DPO)
|
| 233 |
+
|
| 234 |
+
The [`DPOTrainer`] implements preference learning from human feedback.
|
| 235 |
+
|
| 236 |
+
#### With LoRA
|
| 237 |
+
|
| 238 |
+
```bash
|
| 239 |
+
python trl/scripts/dpo.py \
|
| 240 |
+
--model_name_or_path Qwen/Qwen2-0.5B-Instruct \
|
| 241 |
+
--dataset_name trl-lib/ultrafeedback_binarized \
|
| 242 |
+
--learning_rate 5.0e-6 \
|
| 243 |
+
--per_device_train_batch_size 2 \
|
| 244 |
+
--gradient_accumulation_steps 8 \
|
| 245 |
+
--use_peft \
|
| 246 |
+
--lora_r 32 \
|
| 247 |
+
--lora_alpha 16 \
|
| 248 |
+
--output_dir Qwen2-0.5B-DPO-LoRA
|
| 249 |
+
```
|
| 250 |
+
|
| 251 |
+
#### Python Example
|
| 252 |
+
|
| 253 |
+
```python
|
| 254 |
+
from peft import LoraConfig
|
| 255 |
+
from trl import DPOConfig, DPOTrainer
|
| 256 |
+
|
| 257 |
+
# Configure LoRA
|
| 258 |
+
peft_config = LoraConfig(
|
| 259 |
+
r=32,
|
| 260 |
+
lora_alpha=16,
|
| 261 |
+
lora_dropout=0.05,
|
| 262 |
+
bias="none",
|
| 263 |
+
task_type="CAUSAL_LM",
|
| 264 |
+
)
|
| 265 |
+
|
| 266 |
+
# Configure training with higher learning rate for LoRA
|
| 267 |
+
training_args = DPOConfig(
|
| 268 |
+
learning_rate=5.0e-6, # 10x the base rate for DPO with LoRA
|
| 269 |
+
...
|
| 270 |
+
)
|
| 271 |
+
|
| 272 |
+
# Create trainer with PEFT config
|
| 273 |
+
trainer = DPOTrainer(
|
| 274 |
+
model="Qwen/Qwen2-0.5B", # can pass model name or loaded model
|
| 275 |
+
args=training_args,
|
| 276 |
+
train_dataset=dataset,
|
| 277 |
+
peft_config=peft_config, # pass PEFT config here
|
| 278 |
+
)
|
| 279 |
+
trainer.train()
|
| 280 |
+
```
|
| 281 |
+
|
| 282 |
+
**Note:** When using PEFT with DPO, you don't need to provide a separate reference model (`ref_model`). The trainer automatically uses the frozen base model as the reference.
|
| 283 |
+
|
| 284 |
+
</hfoption>
|
| 285 |
+
<hfoption id="grpo">
|
| 286 |
+
|
| 287 |
+
### Group Relative Policy Optimization (GRPO)
|
| 288 |
+
|
| 289 |
+
The `GRPOTrainer` optimizes policies using group-based rewards.
|
| 290 |
+
|
| 291 |
+
#### With LoRA
|
| 292 |
+
|
| 293 |
+
```bash
|
| 294 |
+
python trl/scripts/grpo.py \
|
| 295 |
+
--model_name_or_path Qwen/Qwen2-0.5B \
|
| 296 |
+
--dataset_name trl-lib/math-reasoning \
|
| 297 |
+
--learning_rate 1.0e-5 \
|
| 298 |
+
--per_device_train_batch_size 2 \
|
| 299 |
+
--use_peft \
|
| 300 |
+
--lora_r 32 \
|
| 301 |
+
--lora_alpha 16 \
|
| 302 |
+
--output_dir Qwen2-0.5B-GRPO-LoRA
|
| 303 |
+
```
|
| 304 |
+
|
| 305 |
+
#### Python Example
|
| 306 |
+
|
| 307 |
+
```python
|
| 308 |
+
from peft import LoraConfig
|
| 309 |
+
from trl import GRPOConfig, GRPOTrainer
|
| 310 |
+
|
| 311 |
+
# Configure LoRA
|
| 312 |
+
peft_config = LoraConfig(
|
| 313 |
+
r=32,
|
| 314 |
+
lora_alpha=16,
|
| 315 |
+
lora_dropout=0.05,
|
| 316 |
+
bias="none",
|
| 317 |
+
task_type="CAUSAL_LM",
|
| 318 |
+
)
|
| 319 |
+
|
| 320 |
+
# Configure training with higher learning rate for LoRA
|
| 321 |
+
training_args = GRPOConfig(
|
| 322 |
+
learning_rate=1.0e-5, # 10x the base rate for GRPO with LoRA
|
| 323 |
+
...
|
| 324 |
+
)
|
| 325 |
+
|
| 326 |
+
# Create trainer with PEFT config
|
| 327 |
+
trainer = GRPOTrainer(
|
| 328 |
+
model="Qwen/Qwen2-0.5B", # can pass model name or loaded model
|
| 329 |
+
args=training_args,
|
| 330 |
+
train_dataset=dataset,
|
| 331 |
+
peft_config=peft_config, # pass PEFT config here
|
| 332 |
+
)
|
| 333 |
+
trainer.train()
|
| 334 |
+
```
|
| 335 |
+
|
| 336 |
+
</hfoption>
|
| 337 |
+
</hfoptions>
|
| 338 |
+
|
| 339 |
+
### Proximal Policy Optimization (PPO)
|
| 340 |
+
|
| 341 |
+
#### Multi-Adapter RL Training
|
| 342 |
+
|
| 343 |
+
You can use a single base model with multiple PEFT adapters for the entire PPO algorithm - including retrieving reference logits, computing active logits, and calculating rewards. This approach is useful for memory-efficient RL training.
|
| 344 |
+
|
| 345 |
+
> [!WARNING]
|
| 346 |
+
> This feature is experimental and convergence has not been extensively tested. We encourage the community to share feedback and report any issues.
|
| 347 |
+
|
| 348 |
+
**Requirements**
|
| 349 |
+
|
| 350 |
+
Install PEFT and optionally bitsandbytes for 8-bit models:
|
| 351 |
+
|
| 352 |
+
```bash
|
| 353 |
+
pip install peft bitsandbytes
|
| 354 |
+
```
|
| 355 |
+
|
| 356 |
+
**Training Workflow**
|
| 357 |
+
|
| 358 |
+
The multi-adapter approach requires three stages:
|
| 359 |
+
|
| 360 |
+
1. **Supervised Fine-Tuning (SFT)**: Train a base model on your target domain (e.g., IMDB dataset) using `SFTTrainer`
|
| 361 |
+
2. **Reward Model Training**: Train a reward model adapter using PEFT and `RewardTrainer` (see [reward modeling example](https://github.com/huggingface/trl/tree/main/examples/scripts/reward_modeling.py))
|
| 362 |
+
3. **PPO Training**: Fine-tune new adapters using PPO with the reward adapter
|
| 363 |
+
|
| 364 |
+
> [!IMPORTANT]
|
| 365 |
+
> Use the same base model (architecture and weights) for stages 2 & 3.
|
| 366 |
+
|
| 367 |
+
**Basic Usage**
|
| 368 |
+
|
| 369 |
+
After training your reward adapter and pushing it to the Hub:
|
| 370 |
+
|
| 371 |
+
```python
|
| 372 |
+
from peft import LoraConfig
|
| 373 |
+
from trl.experimental.ppo import PPOTrainer, AutoModelForCausalLMWithValueHead
|
| 374 |
+
|
| 375 |
+
model_name = "huggyllama/llama-7b"
|
| 376 |
+
rm_adapter_id = "trl-lib/llama-7b-hh-rm-adapter"
|
| 377 |
+
|
| 378 |
+
# Configure PPO adapter
|
| 379 |
+
lora_config = LoraConfig(
|
| 380 |
+
r=16,
|
| 381 |
+
lora_alpha=32,
|
| 382 |
+
lora_dropout=0.05,
|
| 383 |
+
bias="none",
|
| 384 |
+
task_type="CAUSAL_LM",
|
| 385 |
+
)
|
| 386 |
+
|
| 387 |
+
# Load model with reward adapter
|
| 388 |
+
model = AutoModelForCausalLMWithValueHead.from_pretrained(
|
| 389 |
+
model_name,
|
| 390 |
+
peft_config=lora_config,
|
| 391 |
+
reward_adapter=rm_adapter_id,
|
| 392 |
+
)
|
| 393 |
+
|
| 394 |
+
trainer = PPOTrainer(model=model, ...)
|
| 395 |
+
```
|
| 396 |
+
|
| 397 |
+
In your training loop, compute rewards using:
|
| 398 |
+
|
| 399 |
+
```python
|
| 400 |
+
rewards = trainer.model.compute_reward_score(**inputs)
|
| 401 |
+
```
|
| 402 |
+
|
| 403 |
+
**Advanced Features**
|
| 404 |
+
|
| 405 |
+
**Quantized Base Models**
|
| 406 |
+
|
| 407 |
+
For memory-efficient training, load the base model in 8-bit or 4-bit while keeping adapters in float32:
|
| 408 |
+
|
| 409 |
+
```python
|
| 410 |
+
from transformers import BitsAndBytesConfig
|
| 411 |
+
|
| 412 |
+
model = AutoModelForCausalLMWithValueHead.from_pretrained(
|
| 413 |
+
model_name,
|
| 414 |
+
peft_config=lora_config,
|
| 415 |
+
reward_adapter=rm_adapter_id,
|
| 416 |
+
quantization_config=BitsAndBytesConfig(load_in_8bit=True),
|
| 417 |
+
)
|
| 418 |
+
```
|
| 419 |
+
|
| 420 |
+
## QLoRA: Quantized Low-Rank Adaptation
|
| 421 |
+
|
| 422 |
+
QLoRA combines 4-bit quantization with LoRA to enable fine-tuning of very large models on consumer hardware. This technique can reduce memory requirements by up to 4x compared to standard LoRA.
|
| 423 |
+
|
| 424 |
+
### How QLoRA Works
|
| 425 |
+
|
| 426 |
+
1. **4-bit Quantization**: The base model is loaded in 4-bit precision using `bitsandbytes`
|
| 427 |
+
2. **Frozen Weights**: The quantized model weights remain frozen during training
|
| 428 |
+
3. **LoRA Adapters**: Only the LoRA adapter parameters are trained in higher precision
|
| 429 |
+
4. **Memory Efficiency**: Enables fine-tuning of models like Llama-70B on a single consumer GPU
|
| 430 |
+
|
| 431 |
+
### Using QLoRA with TRL
|
| 432 |
+
|
| 433 |
+
Simply combine `load_in_4bit=True` with PEFT configuration:
|
| 434 |
+
|
| 435 |
+
#### Command Line
|
| 436 |
+
|
| 437 |
+
```bash
|
| 438 |
+
python trl/scripts/sft.py \
|
| 439 |
+
--model_name_or_path meta-llama/Llama-2-7b-hf \
|
| 440 |
+
--dataset_name trl-lib/Capybara \
|
| 441 |
+
--load_in_4bit \
|
| 442 |
+
--use_peft \
|
| 443 |
+
--lora_r 32 \
|
| 444 |
+
--lora_alpha 16 \
|
| 445 |
+
--per_device_train_batch_size 1 \
|
| 446 |
+
--gradient_accumulation_steps 16 \
|
| 447 |
+
--output_dir Llama-2-7b-QLoRA
|
| 448 |
+
```
|
| 449 |
+
|
| 450 |
+
#### Python Example
|
| 451 |
+
|
| 452 |
+
```python
|
| 453 |
+
import torch
|
| 454 |
+
|
| 455 |
+
from peft import LoraConfig
|
| 456 |
+
from transformers import AutoModelForCausalLM, BitsAndBytesConfig
|
| 457 |
+
from trl import SFTConfig, SFTTrainer
|
| 458 |
+
|
| 459 |
+
# Configure 4-bit quantization
|
| 460 |
+
bnb_config = BitsAndBytesConfig(
|
| 461 |
+
load_in_4bit=True,
|
| 462 |
+
bnb_4bit_quant_type="nf4",
|
| 463 |
+
bnb_4bit_compute_dtype=torch.bfloat16,
|
| 464 |
+
bnb_4bit_use_double_quant=True,
|
| 465 |
+
)
|
| 466 |
+
|
| 467 |
+
# Load model with quantization
|
| 468 |
+
model = AutoModelForCausalLM.from_pretrained(
|
| 469 |
+
"meta-llama/Llama-2-7b-hf",
|
| 470 |
+
quantization_config=bnb_config,
|
| 471 |
+
device_map="auto",
|
| 472 |
+
)
|
| 473 |
+
|
| 474 |
+
# Configure LoRA
|
| 475 |
+
peft_config = LoraConfig(
|
| 476 |
+
r=32,
|
| 477 |
+
lora_alpha=16,
|
| 478 |
+
lora_dropout=0.05,
|
| 479 |
+
bias="none",
|
| 480 |
+
task_type="CAUSAL_LM",
|
| 481 |
+
)
|
| 482 |
+
|
| 483 |
+
# Configure training with higher learning rate for LoRA
|
| 484 |
+
training_args = SFTConfig(
|
| 485 |
+
learning_rate=2.0e-4, # 10x the base rate for QLoRA
|
| 486 |
+
...
|
| 487 |
+
)
|
| 488 |
+
|
| 489 |
+
# Create trainer with PEFT config
|
| 490 |
+
trainer = SFTTrainer(
|
| 491 |
+
model=model,
|
| 492 |
+
args=training_args,
|
| 493 |
+
train_dataset=dataset,
|
| 494 |
+
peft_config=peft_config,
|
| 495 |
+
)
|
| 496 |
+
|
| 497 |
+
trainer.train()
|
| 498 |
+
```
|
| 499 |
+
|
| 500 |
+
### QLoRA Configuration Options
|
| 501 |
+
|
| 502 |
+
The `BitsAndBytesConfig` provides several options to optimize memory and performance:
|
| 503 |
+
|
| 504 |
+
```python
|
| 505 |
+
import torch
|
| 506 |
+
|
| 507 |
+
from transformers import BitsAndBytesConfig
|
| 508 |
+
|
| 509 |
+
bnb_config = BitsAndBytesConfig(
|
| 510 |
+
load_in_4bit=True,
|
| 511 |
+
bnb_4bit_quant_type="nf4", # or "fp4"
|
| 512 |
+
bnb_4bit_compute_dtype=torch.bfloat16, # Compute dtype for 4-bit base models
|
| 513 |
+
bnb_4bit_use_double_quant=True, # Nested quantization for additional memory savings
|
| 514 |
+
)
|
| 515 |
+
```
|
| 516 |
+
|
| 517 |
+
**Configuration Parameters:**
|
| 518 |
+
- `bnb_4bit_quant_type`: Quantization data type (`"nf4"` or `"fp4"`). NF4 is recommended.
|
| 519 |
+
- `bnb_4bit_compute_dtype`: The dtype used for computation. Use `bfloat16` for better training stability.
|
| 520 |
+
- `bnb_4bit_use_double_quant`: Enable nested quantization to save additional ~0.4 bits per parameter.
|
| 521 |
+
|
| 522 |
+
### 8-bit Quantization
|
| 523 |
+
|
| 524 |
+
For slightly higher precision with reduced memory savings, you can use 8-bit quantization:
|
| 525 |
+
|
| 526 |
+
```python
|
| 527 |
+
from transformers import BitsAndBytesConfig, AutoModelForCausalLM
|
| 528 |
+
|
| 529 |
+
bnb_config = BitsAndBytesConfig(load_in_8bit=True)
|
| 530 |
+
|
| 531 |
+
model = AutoModelForCausalLM.from_pretrained(
|
| 532 |
+
"meta-llama/Llama-2-7b-hf",
|
| 533 |
+
quantization_config=bnb_config,
|
| 534 |
+
device_map="auto",
|
| 535 |
+
)
|
| 536 |
+
```
|
| 537 |
+
|
| 538 |
+
Or via command line:
|
| 539 |
+
|
| 540 |
+
```bash
|
| 541 |
+
python trl/scripts/sft.py \
|
| 542 |
+
--model_name_or_path meta-llama/Llama-2-7b-hf \
|
| 543 |
+
--load_in_8bit \
|
| 544 |
+
--use_peft \
|
| 545 |
+
--lora_r 32 \
|
| 546 |
+
--lora_alpha 16
|
| 547 |
+
```
|
| 548 |
+
|
| 549 |
+
## Prompt Tuning
|
| 550 |
+
|
| 551 |
+
Prompt tuning is another PEFT technique that learns soft prompts (continuous embeddings) prepended to the input, while keeping the entire model frozen. This is particularly effective for large models.
|
| 552 |
+
|
| 553 |
+
### How Prompt Tuning Works
|
| 554 |
+
|
| 555 |
+
1. **Virtual Tokens**: Adds learnable continuous embeddings (virtual tokens) to the input
|
| 556 |
+
2. **Frozen Model**: The entire base model remains frozen
|
| 557 |
+
3. **Task-Specific Prompts**: Each task learns its own prompt embeddings
|
| 558 |
+
4. **Extreme Efficiency**: Only the prompt embeddings are trained (typically 8-20 tokens)
|
| 559 |
+
|
| 560 |
+
### Using Prompt Tuning with TRL
|
| 561 |
+
|
| 562 |
+
```python
|
| 563 |
+
from peft import PromptTuningConfig, PromptTuningInit, TaskType
|
| 564 |
+
from trl import SFTConfig, SFTTrainer
|
| 565 |
+
|
| 566 |
+
# Configure Prompt Tuning
|
| 567 |
+
peft_config = PromptTuningConfig(
|
| 568 |
+
task_type=TaskType.CAUSAL_LM,
|
| 569 |
+
prompt_tuning_init=PromptTuningInit.TEXT,
|
| 570 |
+
num_virtual_tokens=8,
|
| 571 |
+
prompt_tuning_init_text="Classify if the tweet is a complaint or not:",
|
| 572 |
+
tokenizer_name_or_path="Qwen/Qwen2-0.5B",
|
| 573 |
+
)
|
| 574 |
+
|
| 575 |
+
# Configure training with higher learning rate for Prompt Tuning
|
| 576 |
+
training_args = SFTConfig(
|
| 577 |
+
learning_rate=2.0e-2, # Prompt Tuning typically uses 1e-2 to 3e-2
|
| 578 |
+
...
|
| 579 |
+
)
|
| 580 |
+
|
| 581 |
+
# Create trainer with PEFT config
|
| 582 |
+
trainer = SFTTrainer(
|
| 583 |
+
model=model,
|
| 584 |
+
args=training_args,
|
| 585 |
+
train_dataset=dataset,
|
| 586 |
+
peft_config=peft_config, # pass PEFT config here
|
| 587 |
+
)
|
| 588 |
+
|
| 589 |
+
trainer.train()
|
| 590 |
+
```
|
| 591 |
+
|
| 592 |
+
### Prompt Tuning Configuration
|
| 593 |
+
|
| 594 |
+
```python
|
| 595 |
+
from peft import PromptTuningConfig, PromptTuningInit, TaskType
|
| 596 |
+
|
| 597 |
+
peft_config = PromptTuningConfig(
|
| 598 |
+
task_type=TaskType.CAUSAL_LM, # Task type
|
| 599 |
+
prompt_tuning_init=PromptTuningInit.TEXT, # Initialize from text
|
| 600 |
+
num_virtual_tokens=8, # Number of virtual tokens
|
| 601 |
+
prompt_tuning_init_text="Your initialization text here",
|
| 602 |
+
tokenizer_name_or_path="model_name",
|
| 603 |
+
)
|
| 604 |
+
```
|
| 605 |
+
|
| 606 |
+
**Configuration Parameters:**
|
| 607 |
+
- `task_type`: The task type (`TaskType.CAUSAL_LM` for language modeling)
|
| 608 |
+
- `prompt_tuning_init`: Initialization method (`TEXT`, `RANDOM`)
|
| 609 |
+
- `num_virtual_tokens`: Number of virtual tokens to prepend (typically 8-20)
|
| 610 |
+
- `prompt_tuning_init_text`: Text to initialize the virtual tokens (when using `TEXT` init)
|
| 611 |
+
- `tokenizer_name_or_path`: Tokenizer for initializing from text
|
| 612 |
+
|
| 613 |
+
### Prompt Tuning vs LoRA
|
| 614 |
+
|
| 615 |
+
| Feature | Prompt Tuning | LoRA |
|
| 616 |
+
|---------|---------------|------|
|
| 617 |
+
| **Parameters Trained** | ~0.001% | ~0.1-1% |
|
| 618 |
+
| **Memory Usage** | Minimal | Low |
|
| 619 |
+
| **Training Speed** | Fastest | Fast |
|
| 620 |
+
| **Model Modification** | None | Adapter layers |
|
| 621 |
+
| **Best For** | Large models, many tasks | General fine-tuning |
|
| 622 |
+
| **Learning Rate** | Higher (1e-2 to 3e-2) | Standard (1e-4 to 3e-4) |
|
| 623 |
+
|
| 624 |
+
## Advanced PEFT Configurations
|
| 625 |
+
|
| 626 |
+
### LoRA Configuration Parameters
|
| 627 |
+
|
| 628 |
+
```python
|
| 629 |
+
from peft import LoraConfig
|
| 630 |
+
|
| 631 |
+
peft_config = LoraConfig(
|
| 632 |
+
r=16, # LoRA rank
|
| 633 |
+
lora_alpha=32, # LoRA scaling factor
|
| 634 |
+
lora_dropout=0.05, # Dropout probability
|
| 635 |
+
bias="none", # Bias training strategy
|
| 636 |
+
task_type="CAUSAL_LM", # Task type
|
| 637 |
+
target_modules=["q_proj", "v_proj"], # Modules to apply LoRA
|
| 638 |
+
modules_to_save=None, # Additional modules to train
|
| 639 |
+
)
|
| 640 |
+
```
|
| 641 |
+
|
| 642 |
+
**Key Parameters:**
|
| 643 |
+
- `r`: LoRA rank (typical values: 8, 16, 32, 64). Higher rank = more parameters but potentially better performance.
|
| 644 |
+
- `lora_alpha`: Scaling factor (typically 2x the rank). Controls the magnitude of LoRA updates.
|
| 645 |
+
- `lora_dropout`: Dropout probability for LoRA layers (typical: 0.05-0.1).
|
| 646 |
+
- `target_modules`: Which modules to apply LoRA to. Common choices:
|
| 647 |
+
- `["q_proj", "v_proj"]`: Attention query and value (memory efficient)
|
| 648 |
+
- `["q_proj", "k_proj", "v_proj", "o_proj"]`: All attention projections
|
| 649 |
+
- `["q_proj", "k_proj", "v_proj", "o_proj", "gate_proj", "up_proj", "down_proj"]`: All linear layers
|
| 650 |
+
- `modules_to_save`: Additional modules to fully train (e.g., `["embed_tokens", "lm_head"]`)
|
| 651 |
+
|
| 652 |
+
### Target Module Selection
|
| 653 |
+
|
| 654 |
+
You can specify which modules to apply LoRA to. Common patterns:
|
| 655 |
+
|
| 656 |
+
```python
|
| 657 |
+
# Minimal (most memory efficient)
|
| 658 |
+
target_modules=["q_proj", "v_proj"]
|
| 659 |
+
|
| 660 |
+
# Attention only
|
| 661 |
+
target_modules=["q_proj", "k_proj", "v_proj", "o_proj"]
|
| 662 |
+
|
| 663 |
+
# All linear layers (best performance, more memory)
|
| 664 |
+
target_modules=["q_proj", "k_proj", "v_proj", "o_proj", "gate_proj", "up_proj", "down_proj"]
|
| 665 |
+
```
|
| 666 |
+
|
| 667 |
+
### Using Command-Line Arguments
|
| 668 |
+
|
| 669 |
+
TRL scripts accept PEFT parameters via command line:
|
| 670 |
+
|
| 671 |
+
```bash
|
| 672 |
+
python trl/scripts/sft.py \
|
| 673 |
+
--model_name_or_path Qwen/Qwen2-0.5B \
|
| 674 |
+
--dataset_name trl-lib/Capybara \
|
| 675 |
+
--use_peft \
|
| 676 |
+
--lora_r 32 \
|
| 677 |
+
--lora_alpha 16 \
|
| 678 |
+
--lora_dropout 0.05 \
|
| 679 |
+
--lora_target_modules q_proj v_proj \
|
| 680 |
+
--output_dir output
|
| 681 |
+
```
|
| 682 |
+
|
| 683 |
+
Available flags:
|
| 684 |
+
- `--use_peft`: Enable PEFT
|
| 685 |
+
- `--lora_r`: LoRA rank (default: 16)
|
| 686 |
+
- `--lora_alpha`: LoRA alpha (default: 32)
|
| 687 |
+
- `--lora_dropout`: LoRA dropout (default: 0.05)
|
| 688 |
+
- `--lora_target_modules`: Target modules (space-separated)
|
| 689 |
+
- `--lora_modules_to_save`: Additional modules to train
|
| 690 |
+
- `--use_rslora`: Enable Rank-Stabilized LoRA
|
| 691 |
+
- `--use_dora`: Enable Weight-Decomposed LoRA (DoRA)
|
| 692 |
+
- `--load_in_4bit`: Enable 4-bit quantization (QLoRA)
|
| 693 |
+
- `--load_in_8bit`: Enable 8-bit quantization
|
| 694 |
+
|
| 695 |
+
## Saving and Loading PEFT Models
|
| 696 |
+
|
| 697 |
+
### Saving
|
| 698 |
+
|
| 699 |
+
After training, save your PEFT adapters:
|
| 700 |
+
|
| 701 |
+
```python
|
| 702 |
+
# Save the adapters
|
| 703 |
+
trainer.save_model("path/to/adapters")
|
| 704 |
+
|
| 705 |
+
# Or manually
|
| 706 |
+
model.save_pretrained("path/to/adapters")
|
| 707 |
+
```
|
| 708 |
+
|
| 709 |
+
This saves only the adapter weights (~few MB) rather than the full model (~several GB).
|
| 710 |
+
|
| 711 |
+
### Loading
|
| 712 |
+
|
| 713 |
+
Load a PEFT model for inference:
|
| 714 |
+
|
| 715 |
+
```python
|
| 716 |
+
from transformers import AutoModelForCausalLM
|
| 717 |
+
from peft import PeftModel
|
| 718 |
+
|
| 719 |
+
# Load base model
|
| 720 |
+
base_model = AutoModelForCausalLM.from_pretrained("Qwen/Qwen2-0.5B")
|
| 721 |
+
|
| 722 |
+
# Load PEFT adapters
|
| 723 |
+
model = PeftModel.from_pretrained(base_model, "path/to/adapters")
|
| 724 |
+
|
| 725 |
+
# Optionally merge adapters into base model for faster inference
|
| 726 |
+
model = model.merge_and_unload()
|
| 727 |
+
```
|
| 728 |
+
|
| 729 |
+
### Pushing to Hub
|
| 730 |
+
|
| 731 |
+
You can easily share your PEFT adapters on the Hugging Face Hub:
|
| 732 |
+
|
| 733 |
+
```python
|
| 734 |
+
# Push adapters to Hub
|
| 735 |
+
model.push_to_hub("username/model-name-lora")
|
| 736 |
+
|
| 737 |
+
# Load from Hub
|
| 738 |
+
from peft import PeftModel
|
| 739 |
+
model = PeftModel.from_pretrained(base_model, "username/model-name-lora")
|
| 740 |
+
```
|
| 741 |
+
|
| 742 |
+
## Multi-GPU Training
|
| 743 |
+
|
| 744 |
+
PEFT works seamlessly with TRL's multi-GPU support through `accelerate`:
|
| 745 |
+
|
| 746 |
+
```bash
|
| 747 |
+
# Configure accelerate
|
| 748 |
+
accelerate config
|
| 749 |
+
|
| 750 |
+
# Launch training
|
| 751 |
+
accelerate launch trl/scripts/sft.py \
|
| 752 |
+
--model_name_or_path Qwen/Qwen2-0.5B \
|
| 753 |
+
--dataset_name trl-lib/Capybara \
|
| 754 |
+
--use_peft \
|
| 755 |
+
--lora_r 32 \
|
| 756 |
+
--lora_alpha 16
|
| 757 |
+
```
|
| 758 |
+
|
| 759 |
+
For QLoRA with multiple GPUs, the base model is automatically sharded:
|
| 760 |
+
|
| 761 |
+
```bash
|
| 762 |
+
accelerate launch trl/scripts/sft.py \
|
| 763 |
+
--model_name_or_path meta-llama/Llama-2-70b-hf \
|
| 764 |
+
--load_in_4bit \
|
| 765 |
+
--use_peft \
|
| 766 |
+
--lora_r 32
|
| 767 |
+
```
|
| 768 |
+
|
| 769 |
+
### Naive Pipeline Parallelism (NPP) for Large Models
|
| 770 |
+
|
| 771 |
+
For very large models (>60B parameters), TRL supports Naive Pipeline Parallelism (NPP), which distributes the model and adapters across multiple GPUs. The activations and gradients are communicated across GPUs, supporting both `int8` and other data types.
|
| 772 |
+
|
| 773 |
+

|
| 774 |
+
|
| 775 |
+
**How to Use NPP**
|
| 776 |
+
|
| 777 |
+
Load your model with a custom `device_map` to split it across multiple devices:
|
| 778 |
+
|
| 779 |
+
```python
|
| 780 |
+
from transformers import AutoModelForCausalLM
|
| 781 |
+
from peft import LoraConfig
|
| 782 |
+
|
| 783 |
+
# Create custom device map (see accelerate documentation)
|
| 784 |
+
device_map = {
|
| 785 |
+
"model.embed_tokens": 0,
|
| 786 |
+
"model.layers.0": 0,
|
| 787 |
+
# ... distribute layers across GPUs
|
| 788 |
+
"lm_head": 0, # Must be on GPU 0
|
| 789 |
+
}
|
| 790 |
+
|
| 791 |
+
model = AutoModelForCausalLM.from_pretrained(
|
| 792 |
+
"meta-llama/Llama-2-70b-hf",
|
| 793 |
+
device_map=device_map,
|
| 794 |
+
peft_config=lora_config,
|
| 795 |
+
)
|
| 796 |
+
```
|
| 797 |
+
|
| 798 |
+
> [!IMPORTANT]
|
| 799 |
+
> - Keep the `lm_head` module on the first GPU (device 0) to avoid errors
|
| 800 |
+
> - See this [tutorial on device maps](https://github.com/huggingface/blog/blob/main/accelerate-large-models.md) for proper configuration
|
| 801 |
+
> - Run training scripts directly (not with `accelerate launch`): `python script.py`
|
| 802 |
+
> - Data Parallelism is not yet supported with NPP
|
| 803 |
+
|
| 804 |
+
## Resources
|
| 805 |
+
|
| 806 |
+
### TRL Examples and Notebooks
|
| 807 |
+
|
| 808 |
+
- **[SFT with LoRA/QLoRA Notebook](https://github.com/huggingface/trl/blob/main/examples/notebooks/sft_trl_lora_qlora.ipynb)** - Complete working example showing both LoRA and QLoRA implementations
|
| 809 |
+
- **[TRL Examples Directory](https://github.com/huggingface/trl/tree/main/examples)** - Collection of training scripts demonstrating PEFT with different trainers
|
| 810 |
+
- **[TRL Cookbook Recipes](https://github.com/huggingface/cookbook/tree/main/notebooks/transformers)** - Step-by-step guides for common PEFT training scenarios
|
| 811 |
+
|
| 812 |
+
### Documentation
|
| 813 |
+
|
| 814 |
+
- [PEFT Documentation](https://huggingface.co/docs/peft) - Official PEFT library documentation
|
| 815 |
+
- [TRL Documentation](https://huggingface.co/docs/trl) - Complete TRL documentation with trainer guides
|
| 816 |
+
- [LoRA Without Regret](lora_without_regret) - Best practices for using LoRA effectively
|
| 817 |
+
|
| 818 |
+
### Research Papers
|
| 819 |
+
|
| 820 |
+
- [LoRA Paper](https://huggingface.co/papers/2106.09685) - Original LoRA methodology and results
|
| 821 |
+
- [QLoRA Paper](https://huggingface.co/papers/2305.14314) - Efficient finetuning with 4-bit quantization
|
| 822 |
+
- [Prompt Tuning Paper](https://huggingface.co/papers/2104.08691) - The Power of Scale for Parameter-Efficient Prompt Tuning
|
tasks/tasksmith-1c108f674e97/tests/source/docs/source/ppo_trainer.md
ADDED
|
@@ -0,0 +1,252 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# PPO Trainer
|
| 2 |
+
|
| 3 |
+
[](https://huggingface.co/models?other=ppo,trl)
|
| 4 |
+
|
| 5 |
+
TRL supports training LLMs with [Proximal Policy Optimization (PPO)](https://huggingface.co/papers/1707.06347).
|
| 6 |
+
|
| 7 |
+
References:
|
| 8 |
+
|
| 9 |
+
- [Fine-Tuning Language Models from Human Preferences](https://github.com/openai/lm-human-preferences)
|
| 10 |
+
- [Learning to Summarize from Human Feedback](https://github.com/openai/summarize-from-feedback)
|
| 11 |
+
- [The N Implementation Details of RLHF with PPO](https://huggingface.co/blog/the_n_implementation_details_of_rlhf_with_ppo)
|
| 12 |
+
- [The N+ Implementation Details of RLHF with PPO: A Case Study on TL;DR Summarization](https://huggingface.co/papers/2403.17031)
|
| 13 |
+
|
| 14 |
+
## Get started
|
| 15 |
+
|
| 16 |
+
To just run a PPO script to make sure the trainer can run, you can run the following command to train a PPO model with a dummy reward model.
|
| 17 |
+
|
| 18 |
+
```bash
|
| 19 |
+
python examples/scripts/ppo/ppo.py \
|
| 20 |
+
--dataset_name trl-internal-testing/descriptiveness-sentiment-trl-style \
|
| 21 |
+
--dataset_train_split descriptiveness \
|
| 22 |
+
--learning_rate 3e-6 \
|
| 23 |
+
--num_ppo_epochs 1 \
|
| 24 |
+
--num_mini_batches 1 \
|
| 25 |
+
--output_dir models/minimal/ppo \
|
| 26 |
+
--per_device_train_batch_size 64 \
|
| 27 |
+
--gradient_accumulation_steps 1 \
|
| 28 |
+
--total_episodes 10000 \
|
| 29 |
+
--model_name_or_path EleutherAI/pythia-1b-deduped \
|
| 30 |
+
--sft_model_path EleutherAI/pythia-1b-deduped \
|
| 31 |
+
--reward_model_path EleutherAI/pythia-1b-deduped \
|
| 32 |
+
--missing_eos_penalty 1.0
|
| 33 |
+
```
|
| 34 |
+
|
| 35 |
+
## Explanation of the logged metrics
|
| 36 |
+
|
| 37 |
+
The logged metrics are as follows. Here is an example [tracked run at Weights and Biases](https://wandb.ai/huggingface/trl/runs/dd2o3g35)
|
| 38 |
+
|
| 39 |
+
- `eps`: Tracks the number of episodes per second.
|
| 40 |
+
- `objective/kl`: The mean Kullback-Leibler (KL) divergence between the current policy and reference policy.
|
| 41 |
+
- `objective/entropy`: The mean entropy of the policy, indicating the randomness of the actions chosen by the policy.
|
| 42 |
+
- `objective/non_score_reward`: The mean reward from non-score-related sources, basically `beta * kl.sum(1)`, where `beta` is the KL penalty coefficient and `kl` is the per-token KL divergence.
|
| 43 |
+
- `objective/rlhf_reward`: The mean RLHF reward, which is `score - non_score_reward`.
|
| 44 |
+
- `objective/scores`: The mean scores returned by the reward model / environment.
|
| 45 |
+
- `policy/approxkl_avg`: The average approximate KL divergence between consecutive PPO policies. Note that this is not the same as `objective/kl`.
|
| 46 |
+
- `policy/clipfrac_avg`: The average fraction of policy updates that are clipped, indicating how often the policy updates are constrained to prevent large changes.
|
| 47 |
+
- `loss/policy_avg`: The average policy loss, indicating how well the policy is performing.
|
| 48 |
+
- `loss/value_avg`: The average value loss, indicating the difference between the predicted value and the actual reward.
|
| 49 |
+
- `val/clipfrac_avg`: The average fraction of value function updates that are clipped, similar to policy/clipfrac_avg but for the value function.
|
| 50 |
+
- `policy/entropy_avg`: The average entropy of the policy during training, indicating how diverse the policy's actions are.
|
| 51 |
+
- `val/ratio`: The mean ratio of the current policy probability to the old policy probability, providing a measure of how much the policy has changed.
|
| 52 |
+
- `val/ratio_var`: The variance of the `val/ratio`, indicating the variability in policy changes.
|
| 53 |
+
- `val/num_eos_tokens`: The number of end-of-sequence (EOS) tokens generated, which can indicate the number of complete responses.
|
| 54 |
+
- `lr`: lr: The current learning rate used by the optimizer.
|
| 55 |
+
- `episode`: episode: The current episode count in the training process.
|
| 56 |
+
|
| 57 |
+
## Cookbook
|
| 58 |
+
|
| 59 |
+
- Debugging TIP: `objective/rlhf_reward`: this is the ultimate objective of the RLHF training. If training works as intended, this metric should keep going up.
|
| 60 |
+
- Debugging TIP: `val/ratio`: this number should float around 1.0, and it gets clipped by `--cliprange 0.2` with PPO's surrogate loss. So if this `ratio` is too high like 2.0 or 1000.0 or too small like 0.1, it means the updates between consecutive policies are too drastic. You should try understand why this is happening and try to fix it.
|
| 61 |
+
- Memory TIP: If you are running out of memory, you can try to reduce the `--per_device_train_batch_size` or increase the `--gradient_accumulation_steps` to reduce the memory footprint.
|
| 62 |
+
- Memory TIP: If you have multiple GPUs, you can also run training with DeepSpeed stage 3 to reduce the memory footprint `accelerate launch --config_file examples/accelerate_configs/deepspeed_zero3.yaml`.
|
| 63 |
+
- Usage TIP: We recommend to use the "EOS trick" via `--missing_eos_penalty`, which subtracts a static scalar penalty from the score of completions that do not end with an EOS token. This can help the model learn to generate more coherent completions.
|
| 64 |
+
|
| 65 |
+
## What is my model doing exactly?
|
| 66 |
+
|
| 67 |
+
To help you understand what your model is doing, we periodically log some sample completions from the model. Here is an example of a completion. In an example [tracked run at Weights and Biases](https://wandb.ai/huggingface/trl/runs/dd2o3g35), it looks like the following, allowing you to see the model's response at different stages of training. By default we generate `--num_sample_generations 10` during training, but you can customize the number of generations.
|
| 68 |
+
|
| 69 |
+

|
| 70 |
+
|
| 71 |
+
In the logs the sampled generations look like
|
| 72 |
+
|
| 73 |
+
```txt
|
| 74 |
+
┏━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━┳━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━┳━━━━━━━━━━┓
|
| 75 |
+
┃ query ┃ model response ┃ score ┃
|
| 76 |
+
┡━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━╇━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━╇━━━━━━━━━━┩
|
| 77 |
+
│ SUBREDDIT: r/AskReddit │ I'm in love with a friend, and │ 3.921875 │
|
| 78 |
+
│ │ I don't know how to get rid of │ │
|
| 79 |
+
│ TITLE: How do you get someone │ those feelings. I'm │ │
|
| 80 |
+
│ out of your head? │ desperate.<|endoftext|>[PAD][P… │ │
|
| 81 |
+
│ │ │ │
|
| 82 |
+
│ POST: Hi, │ │ │
|
| 83 |
+
│ I'm 22, and I have been with my │ │ │
|
| 84 |
+
│ girlfriend for 5 years now. We │ │ │
|
| 85 |
+
│ recently moved together. We've │ │ │
|
| 86 |
+
│ always loved each other │ │ │
|
| 87 |
+
│ intensely. │ │ │
|
| 88 |
+
│ │ │ │
|
| 89 |
+
│ Problem, I recently started to │ │ │
|
| 90 |
+
│ have feelings for an other │ │ │
|
| 91 |
+
│ person (a friend). This person │ │ │
|
| 92 |
+
│ has had a boyfriend for now 3 │ │ │
|
| 93 |
+
│ years, and has absolutely no │ │ │
|
| 94 |
+
│ ideas. Those feelings were so │ │ │
|
| 95 |
+
│ strong, it was hard to hide │ │ │
|
| 96 |
+
│ them. After 2 months of me │ │ │
|
| 97 |
+
│ being distant and really sad, │ │ │
|
| 98 |
+
│ my girlfriend forced me to say │ │ │
|
| 99 |
+
│ what was bothering me. I'm not │ │ │
|
| 100 |
+
│ a good liar, and now she knows. │ │ │
|
| 101 |
+
│ │ │ │
|
| 102 |
+
│ We decided to give us a week │ │ │
|
| 103 |
+
│ alone, I went to my parents. │ │ │
|
| 104 |
+
│ │ │ │
|
| 105 |
+
│ Now, I'm completely lost. I │ │ │
|
| 106 |
+
│ keep on thinking about this │ │ │
|
| 107 |
+
│ person, and I hate that. I │ │ │
|
| 108 |
+
│ would like for those feelings │ │ │
|
| 109 |
+
│ to go away, to leave me alone. │ │ │
|
| 110 |
+
│ But I can't. │ │ │
|
| 111 |
+
│ │ │ │
|
| 112 |
+
│ What do I do? It's been 3 │ │ │
|
| 113 |
+
│ months now, and I'm just │ │ │
|
| 114 |
+
│ desperate. │ │ │
|
| 115 |
+
│ │ │ │
|
| 116 |
+
│ TL;DR: │ │ │
|
| 117 |
+
├─────────────────────────────────┼─────────────────────────────────┼──────────┤
|
| 118 |
+
│ SUBREDDIT: r/pettyrevenge │ My mom woke me up with a loud │ 6.84375 │
|
| 119 |
+
│ │ TV. I blasted Gangnam Style on │ │
|
| 120 |
+
│ TITLE: So, my mom woke me up │ repeat, with the bass cranked │ │
|
| 121 |
+
│ with a loud TV. │ up as high as it could │ │
|
| 122 |
+
│ │ go.<|endoftext|>[PAD][PAD][PAD… │ │
|
| 123 |
+
│ POST: She was in her living │ │ │
|
| 124 |
+
│ room, watching TV. This was at │ │ │
|
| 125 |
+
│ about 8:30 in the morning, and │ │ │
|
| 126 |
+
│ she was exercising. She turned │ │ │
|
| 127 |
+
│ the TV up extra loud to hear it │ │ │
|
| 128 |
+
│ over her excercycle, and woke │ │ │
|
| 129 |
+
│ me up. I went in there asking │ │ │
|
| 130 |
+
│ for her to turn it down. She │ │ │
|
| 131 |
+
│ said she didn't have to; I │ │ │
|
| 132 |
+
│ explained that I always used │ │ │
|
| 133 |
+
│ headphones so she didn't have │ │ │
|
| 134 |
+
│ to deal with my noise and that │ │ │
|
| 135 |
+
│ she should give me a little │ │ │
|
| 136 |
+
│ more respect, given that I paid │ │ │
|
| 137 |
+
│ rent at the time. │ │ │
|
| 138 |
+
│ │ │ │
|
| 139 |
+
│ She disagreed. I went back to │ │ │
|
| 140 |
+
│ my room, rather pissed off at │ │ │
|
| 141 |
+
│ the lack of equality. I had no │ │ │
|
| 142 |
+
│ lock on my door; but I had a │ │ │
|
| 143 |
+
│ dresser right next to it, so I │ │ │
|
| 144 |
+
│ pulled one of the drawers out │ │ │
|
| 145 |
+
│ enough so that it caused the │ │ │
|
| 146 |
+
│ door to not be openable. Then, │ │ │
|
| 147 |
+
│ I turned my speakers up really │ │ │
|
| 148 |
+
│ loud and blasted Gangnam Style │ │ │
|
| 149 |
+
│ on repeat, with the bass │ │ │
|
| 150 |
+
│ cranked up as high as it could │ │ │
|
| 151 |
+
│ go. │ │ │
|
| 152 |
+
│ │ │ │
|
| 153 |
+
│ If you hate Gangnam Style for │ │ │
|
| 154 |
+
│ being overplayed, you will see │ │ │
|
| 155 |
+
│ why I chose that particular │ │ │
|
| 156 |
+
│ song. I personally don't mind │ │ │
|
| 157 |
+
│ it. But here's the thing about │ │ │
|
| 158 |
+
│ my bass; it vibrates the walls, │ │ │
|
| 159 |
+
│ making one hell of a lot of │ │ │
|
| 160 |
+
│ noise. Needless to say, my mom │ │ │
|
| 161 |
+
│ was not pleased and shut off │ │ │
|
| 162 |
+
│ the internet. But it was oh so │ │ │
|
| 163 |
+
│ worth it. │ │ │
|
| 164 |
+
│ │ │ │
|
| 165 |
+
│ TL;DR: │ │ │
|
| 166 |
+
└─────────────────────────────────┴─────────────────────────────────┴──────────┘
|
| 167 |
+
```
|
| 168 |
+
|
| 169 |
+
## Implementation details
|
| 170 |
+
|
| 171 |
+
This PPO implementation is based on the [The N+ Implementation Details of RLHF with PPO: A Case Study on TL;DR Summarization](https://huggingface.co/papers/2403.17031).
|
| 172 |
+
|
| 173 |
+
## Benchmark experiments
|
| 174 |
+
|
| 175 |
+
To validate the PPO implementation works, we ran experiment on the 1B model. Here are the command we used to run the experiment. We take the SFT / RM models directly from [The N+ Implementation Details of RLHF with PPO: A Case Study on TL;DR Summarization](https://huggingface.co/papers/2403.17031).
|
| 176 |
+
|
| 177 |
+
```shell
|
| 178 |
+
accelerate launch --config_file examples/accelerate_configs/deepspeed_zero2.yaml \
|
| 179 |
+
examples/scripts/ppo/ppo_tldr.py \
|
| 180 |
+
--dataset_name trl-lib/tldr \
|
| 181 |
+
--dataset_test_split validation \
|
| 182 |
+
--output_dir models/minimal/ppo_tldr \
|
| 183 |
+
--learning_rate 3e-6 \
|
| 184 |
+
--per_device_train_batch_size 16 \
|
| 185 |
+
--gradient_accumulation_steps 4 \
|
| 186 |
+
--total_episodes 1000000 \
|
| 187 |
+
--model_name_or_path EleutherAI/pythia-1b-deduped \
|
| 188 |
+
--sft_model_path cleanrl/EleutherAI_pythia-1b-deduped__sft__tldr \
|
| 189 |
+
--reward_model_path cleanrl/EleutherAI_pythia-1b-deduped__reward__tldr \
|
| 190 |
+
--local_rollout_forward_batch_size 16 \
|
| 191 |
+
--missing_eos_penalty 1.0 \
|
| 192 |
+
--stop_token eos \
|
| 193 |
+
--eval_strategy steps \
|
| 194 |
+
--eval_steps 100
|
| 195 |
+
```
|
| 196 |
+
|
| 197 |
+
Checkpoints and experiment tracking are available at:
|
| 198 |
+
|
| 199 |
+
- [🤗 Model checkpoint](https://huggingface.co/trl-lib/ppo_tldr)
|
| 200 |
+
- [🐝 Tracked experiment](https://wandb.ai/huggingface/trl/runs/dd2o3g35)
|
| 201 |
+
|
| 202 |
+
The PPO checkpoint gets a 64.7% preferred rate vs the 33.0% preference rate of the SFT checkpoint (evaluated with GPT-4o mini as a judge). This is a good sign that the PPO training is working as intended.
|
| 203 |
+
|
| 204 |
+
Metrics:
|
| 205 |
+
|
| 206 |
+

|
| 207 |
+
|
| 208 |
+
```bash
|
| 209 |
+
# pip install openrlbenchmark==0.2.1a5
|
| 210 |
+
# see https://github.com/openrlbenchmark/openrlbenchmark#get-started for documentation
|
| 211 |
+
# to use it, change `?we=huggingface&wpn=trl` to your own project and `?tag=pr-1540` to your own tag
|
| 212 |
+
python -m openrlbenchmark.rlops_multi_metrics \
|
| 213 |
+
--filters '?we=huggingface&wpn=trl&xaxis=train/episode&ceik=output_dir&cen=sft_model_path&metrics=train/objective/rlhf_reward&metrics=train/objective/scores&metrics=train/objective/kl&metrics=train/objective/non_score_reward&metrics=train/objective/entropy&metrics=train/policy/approxkl_avg&metrics=train/policy/clipfrac_avg&metrics=train/loss/policy_avg&metrics=train/loss/value_avg&metrics=train/val/clipfrac_avg&metrics=train/policy/entropy_avg&metrics=train/val/ratio&metrics=train/val/ratio_var&metrics=train/val/num_eos_tokens&metrics=train/lr&metrics=train/eps' \
|
| 214 |
+
"cleanrl/EleutherAI_pythia-1b-deduped__sft__tldr?tag=pr-1540" \
|
| 215 |
+
--env-ids models/minimal/ppo_tldr \
|
| 216 |
+
--pc.ncols 4 \
|
| 217 |
+
--pc.ncols-legend 1 \
|
| 218 |
+
--pc.xlabel "Episode" \
|
| 219 |
+
--output-filename benchmark/trl/pr-1540/ppo \
|
| 220 |
+
--scan-history
|
| 221 |
+
```
|
| 222 |
+
|
| 223 |
+
## PPOTrainer
|
| 224 |
+
|
| 225 |
+
[[autodoc]] experimental.ppo.PPOTrainer
|
| 226 |
+
- train
|
| 227 |
+
- save_model
|
| 228 |
+
- push_to_hub
|
| 229 |
+
|
| 230 |
+
## PPOConfig
|
| 231 |
+
|
| 232 |
+
[[autodoc]] experimental.ppo.PPOConfig
|
| 233 |
+
|
| 234 |
+
## PreTrainedModelWrapper
|
| 235 |
+
|
| 236 |
+
[[autodoc]] experimental.ppo.PreTrainedModelWrapper
|
| 237 |
+
|
| 238 |
+
## AutoModelForCausalLMWithValueHead
|
| 239 |
+
|
| 240 |
+
[[autodoc]] experimental.ppo.AutoModelForCausalLMWithValueHead
|
| 241 |
+
- __init__
|
| 242 |
+
- forward
|
| 243 |
+
- generate
|
| 244 |
+
- _init_weights
|
| 245 |
+
|
| 246 |
+
## AutoModelForSeq2SeqLMWithValueHead
|
| 247 |
+
|
| 248 |
+
[[autodoc]] experimental.ppo.AutoModelForSeq2SeqLMWithValueHead
|
| 249 |
+
- __init__
|
| 250 |
+
- forward
|
| 251 |
+
- generate
|
| 252 |
+
- _init_weights
|
tasks/tasksmith-1c108f674e97/tests/source/docs/source/prm_trainer.md
ADDED
|
@@ -0,0 +1,122 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# PRM Trainer
|
| 2 |
+
|
| 3 |
+
[](https://huggingface.co/models?other=prm,trl)
|
| 4 |
+
|
| 5 |
+
> [!WARNING]
|
| 6 |
+
> PRM Trainer is an experimental API which is subject to change at any time.
|
| 7 |
+
|
| 8 |
+
## Overview
|
| 9 |
+
|
| 10 |
+
Process-supervised Reward Models (PRM) were proposed in [Solving math word problems with process- and outcome-based feedback](https://huggingface.co/papers/2211.14275) by Jonathan Uesato, Nate Kushman, Ramana Kumar, Francis Song, Noah Siegel, Lisa Wang, Antonia Creswell, Geoffrey Irving, and Irina Higgins.
|
| 11 |
+
|
| 12 |
+
The abstract from the paper is the following:
|
| 13 |
+
|
| 14 |
+
> Recent work has shown that asking language models to generate reasoning steps improves performance on many reasoning tasks. When moving beyond prompting, this raises the question of how we should supervise such models: outcome-based approaches which supervise the final result, or process-based approaches which supervise the reasoning process itself? Differences between these approaches might naturally be expected not just in final-answer errors but also in reasoning errors, which can be difficult to detect and are problematic in many real-world domains such as education. We run the first comprehensive comparison between process- and outcome-based approaches trained on a natural language task, GSM8K. We find that pure outcome-based supervision produces similar final-answer error rates with less label supervision. However, for correct reasoning steps we find it necessary to use processbased supervision or supervision from learned reward models that emulate process-based feedback. In total, we improve the previous best results from 16.8% → 12.7% final-answer error and 14.0% → 3.4% reasoning error among final-answer-correct solutions.
|
| 15 |
+
|
| 16 |
+
This post-training method was contributed by [Gaetan Lopez](https://github.com/gaetanlop), [Lewis Tunstall](https://huggingface.co/lewtun), [Quentin Gallouédec](https://huggingface.co/qgallouedec) and [Agustín Piqueres](https://huggingface.co/plaguss).
|
| 17 |
+
|
| 18 |
+
## Quick start
|
| 19 |
+
|
| 20 |
+
This example demonstrates how to train a model using the PRM method. We use the [Qwen 0.5B model](https://huggingface.co/Qwen/Qwen2-0.5B) as the base model. We use the stepwise supervision data from the [Math Shepherd dataset](https://huggingface.co/datasets/trl-lib/math_shepherd). You can view the data in the dataset here:
|
| 21 |
+
|
| 22 |
+
<iframe
|
| 23 |
+
src="https://huggingface.co/datasets/trl-lib/math_shepherd/embed/viewer/default/train?row=0"
|
| 24 |
+
frameborder="0"
|
| 25 |
+
width="100%"
|
| 26 |
+
height="560px"
|
| 27 |
+
></iframe>
|
| 28 |
+
|
| 29 |
+
Below is the script to train the model:
|
| 30 |
+
|
| 31 |
+
```python
|
| 32 |
+
# train_prm.py
|
| 33 |
+
from datasets import load_dataset
|
| 34 |
+
from trl.experimental.prm import PRMConfig, PRMTrainer
|
| 35 |
+
from transformers import AutoModelForTokenClassification, AutoTokenizer
|
| 36 |
+
|
| 37 |
+
model = AutoModelForTokenClassification.from_pretrained("Qwen/Qwen2-0.5B", num_labels=2)
|
| 38 |
+
tokenizer = AutoTokenizer.from_pretrained("Qwen/Qwen2-0.5B")
|
| 39 |
+
train_dataset = load_dataset("trl-lib/math_shepherd", split="train[:10%]")
|
| 40 |
+
|
| 41 |
+
training_args = PRMConfig(output_dir="Qwen2-0.5B-Reward-Math-Sheperd")
|
| 42 |
+
trainer = PRMTrainer(model=model, args=training_args, processing_class=tokenizer, train_dataset=train_dataset)
|
| 43 |
+
trainer.train()
|
| 44 |
+
```
|
| 45 |
+
|
| 46 |
+
Execute the script using the following command:
|
| 47 |
+
|
| 48 |
+
```bash
|
| 49 |
+
accelerate launch train_prm.py
|
| 50 |
+
```
|
| 51 |
+
|
| 52 |
+
Distributed across 8 GPUs, the training takes approximately 1 hour.
|
| 53 |
+
|
| 54 |
+
To see how the [trained model](https://huggingface.co/trl-lib/Qwen2-0.5B-Reward-Math-Sheperd) performs, you can use the following script.
|
| 55 |
+
|
| 56 |
+
```python
|
| 57 |
+
from datasets import load_dataset
|
| 58 |
+
from transformers import pipeline
|
| 59 |
+
|
| 60 |
+
pipe = pipeline("token-classification", model="trl-lib/Qwen2-0.5B-Reward-Math-Sheperd")
|
| 61 |
+
dataset = load_dataset("trl-lib/math_shepherd")
|
| 62 |
+
example = {
|
| 63 |
+
"prompt": "Musa is the class teacher of a class of 45 students. He wants to split them into three groups by age. If a third of the class is under 11 years, and two-fifths are above 11 but under 13, how many students will be in the third group (13 years and above)?",
|
| 64 |
+
"completions": [
|
| 65 |
+
"Step 1: A third of the class is under 11 years because 11 - 1/3 = <<11-1/3=7>>7.",
|
| 66 |
+
"Step 2: Two-fifths of the class are above 11 but under 13 because 2/5 * 11 = <<2/5*11=8>>8.",
|
| 67 |
+
"Step 3: There are 45 students, so the third group will have 45 - 7 - 8 = <<45-7-8=20>>20 students. The answer is: 20",
|
| 68 |
+
],
|
| 69 |
+
"labels": [True, False, False],
|
| 70 |
+
}
|
| 71 |
+
|
| 72 |
+
|
| 73 |
+
separator = "\n" # It's important to use the same separator as the one used during training
|
| 74 |
+
|
| 75 |
+
for idx in range(1, len(example["completions"]) + 1):
|
| 76 |
+
steps = example["completions"][0:idx]
|
| 77 |
+
text = separator.join((example["prompt"], *steps)) + separator # Add a separator between the prompt and each steps
|
| 78 |
+
pred_entity = pipe(text)[-1]["entity"]
|
| 79 |
+
pred = {"LABEL_0": False, "LABEL_1": True}[pred_entity]
|
| 80 |
+
label = example["labels"][idx - 1]
|
| 81 |
+
print(f"Step {idx}\tPredicted: {pred} \tLabel: {label}")
|
| 82 |
+
```
|
| 83 |
+
|
| 84 |
+
```text
|
| 85 |
+
Step 1 Predicted: True Label: True
|
| 86 |
+
Step 2 Predicted: False Label: False
|
| 87 |
+
Step 3 Predicted: False Label: False
|
| 88 |
+
```
|
| 89 |
+
|
| 90 |
+
It's a win!
|
| 91 |
+
|
| 92 |
+
## Expected dataset type
|
| 93 |
+
|
| 94 |
+
PRM requires a [stepwise supervision](dataset_formats#stepwise-supervision).
|
| 95 |
+
The dataset should contain the following columns: `prompt`, `completions` and `labels`, where `completions` contains a list of reasoning steps and `labels` a list of booleans or floats indicating the correctness of each step.
|
| 96 |
+
|
| 97 |
+
The [`experimental.prm.PRMTrainer`] only supports [standard](dataset_formats#standard) dataset format.
|
| 98 |
+
|
| 99 |
+
## Example script
|
| 100 |
+
|
| 101 |
+
We provide an example script to train a model using the PRM method. The script is available in [`examples/scripts/prm.py`](https://github.com/huggingface/trl/blob/main/examples/scripts/prm.py)
|
| 102 |
+
|
| 103 |
+
To use the PRM script with the [Qwen2 0.5B model](https://huggingface.co/Qwen/Qwen2-0.5B) on the [Math Shepherd dataset](https://huggingface.co/datasets/trl-lib/math_shepherd), run the following command:
|
| 104 |
+
|
| 105 |
+
```bash
|
| 106 |
+
accelerate launch examples/scripts/prm.py \
|
| 107 |
+
--model_name_or_path Qwen/Qwen2-0.5B \
|
| 108 |
+
--dataset_name trl-lib/math_shepherd \
|
| 109 |
+
--num_train_epochs 1 \
|
| 110 |
+
--output_dir Qwen2-0.5B-Reward-Math-Sheperd
|
| 111 |
+
```
|
| 112 |
+
|
| 113 |
+
## PRMTrainer
|
| 114 |
+
|
| 115 |
+
[[autodoc]] experimental.prm.PRMTrainer
|
| 116 |
+
- train
|
| 117 |
+
- save_model
|
| 118 |
+
- push_to_hub
|
| 119 |
+
|
| 120 |
+
## PRMConfig
|
| 121 |
+
|
| 122 |
+
[[autodoc]] experimental.prm.PRMConfig
|
tasks/tasksmith-1c108f674e97/tests/source/docs/source/ptt_integration.md
ADDED
|
@@ -0,0 +1,193 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Post-Training Toolkit Integration
|
| 2 |
+
|
| 3 |
+
[Post-Training Toolkit](https://github.com/microsoft/post-training-toolkit) is a diagnostic and observability layer for RLHF training runs. Add one callback to any TRL trainer and get **auto-metrics**, **crash postmortems**, and **literature-backed heuristics**—without writing glue code.
|
| 4 |
+
|
| 5 |
+
It was built to operationalize the debugging patterns we found most useful when running post-training at scale.
|
| 6 |
+
|
| 7 |
+
## Usage
|
| 8 |
+
|
| 9 |
+
1. First, install Post-Training Toolkit:
|
| 10 |
+
|
| 11 |
+
```bash
|
| 12 |
+
pip install post-training-toolkit
|
| 13 |
+
```
|
| 14 |
+
|
| 15 |
+
2. Add one callback to your trainer. That's it!
|
| 16 |
+
|
| 17 |
+
<hfoptions id="trainer">
|
| 18 |
+
<hfoption id="DPO">
|
| 19 |
+
|
| 20 |
+
```python
|
| 21 |
+
from post_training_toolkit import DiagnosticsCallback
|
| 22 |
+
from trl import DPOTrainer
|
| 23 |
+
|
| 24 |
+
trainer = DPOTrainer(
|
| 25 |
+
model=model,
|
| 26 |
+
args=training_args,
|
| 27 |
+
callbacks=[DiagnosticsCallback()], # ← Just add this
|
| 28 |
+
...
|
| 29 |
+
)
|
| 30 |
+
trainer.train()
|
| 31 |
+
```
|
| 32 |
+
|
| 33 |
+
</hfoption>
|
| 34 |
+
<hfoption id="PPO">
|
| 35 |
+
|
| 36 |
+
```python
|
| 37 |
+
from post_training_toolkit import DiagnosticsCallback
|
| 38 |
+
from trl.experimental.ppo import PPOTrainer
|
| 39 |
+
|
| 40 |
+
trainer = PPOTrainer(
|
| 41 |
+
model=model,
|
| 42 |
+
args=training_args,
|
| 43 |
+
callbacks=[DiagnosticsCallback()], # ← Just add this
|
| 44 |
+
...
|
| 45 |
+
)
|
| 46 |
+
trainer.train()
|
| 47 |
+
```
|
| 48 |
+
|
| 49 |
+
</hfoption>
|
| 50 |
+
<hfoption id="SFT">
|
| 51 |
+
|
| 52 |
+
```python
|
| 53 |
+
from post_training_toolkit import DiagnosticsCallback
|
| 54 |
+
from trl import SFTTrainer
|
| 55 |
+
|
| 56 |
+
trainer = SFTTrainer(
|
| 57 |
+
model=model,
|
| 58 |
+
args=training_args,
|
| 59 |
+
callbacks=[DiagnosticsCallback()], # ← Just add this
|
| 60 |
+
...
|
| 61 |
+
)
|
| 62 |
+
trainer.train()
|
| 63 |
+
```
|
| 64 |
+
|
| 65 |
+
</hfoption>
|
| 66 |
+
<hfoption id="ORPO">
|
| 67 |
+
|
| 68 |
+
```python
|
| 69 |
+
from post_training_toolkit import DiagnosticsCallback
|
| 70 |
+
from trl.experimental.orpo import ORPOTrainer
|
| 71 |
+
|
| 72 |
+
trainer = ORPOTrainer(
|
| 73 |
+
model=model,
|
| 74 |
+
args=training_args,
|
| 75 |
+
callbacks=[DiagnosticsCallback()], # ← Just add this
|
| 76 |
+
...
|
| 77 |
+
)
|
| 78 |
+
trainer.train()
|
| 79 |
+
```
|
| 80 |
+
|
| 81 |
+
</hfoption>
|
| 82 |
+
<hfoption id="KTO">
|
| 83 |
+
|
| 84 |
+
```python
|
| 85 |
+
from post_training_toolkit import DiagnosticsCallback
|
| 86 |
+
from trl import KTOTrainer
|
| 87 |
+
|
| 88 |
+
trainer = KTOTrainer(
|
| 89 |
+
model=model,
|
| 90 |
+
args=training_args,
|
| 91 |
+
callbacks=[DiagnosticsCallback()], # ← Just add this
|
| 92 |
+
...
|
| 93 |
+
)
|
| 94 |
+
trainer.train()
|
| 95 |
+
```
|
| 96 |
+
|
| 97 |
+
</hfoption>
|
| 98 |
+
<hfoption id="CPO">
|
| 99 |
+
|
| 100 |
+
```python
|
| 101 |
+
from post_training_toolkit import DiagnosticsCallback
|
| 102 |
+
from trl.experimental.cpo import CPOTrainer
|
| 103 |
+
|
| 104 |
+
trainer = CPOTrainer(
|
| 105 |
+
model=model,
|
| 106 |
+
args=training_args,
|
| 107 |
+
callbacks=[DiagnosticsCallback()], # ← Just add this
|
| 108 |
+
...
|
| 109 |
+
)
|
| 110 |
+
trainer.train()
|
| 111 |
+
```
|
| 112 |
+
|
| 113 |
+
</hfoption>
|
| 114 |
+
<hfoption id="GRPO">
|
| 115 |
+
|
| 116 |
+
```python
|
| 117 |
+
from post_training_toolkit import DiagnosticsCallback
|
| 118 |
+
from trl import GRPOTrainer
|
| 119 |
+
|
| 120 |
+
trainer = GRPOTrainer(
|
| 121 |
+
model=model,
|
| 122 |
+
args=training_args,
|
| 123 |
+
callbacks=[DiagnosticsCallback()], # ← Just add this
|
| 124 |
+
...
|
| 125 |
+
)
|
| 126 |
+
trainer.train()
|
| 127 |
+
```
|
| 128 |
+
|
| 129 |
+
</hfoption>
|
| 130 |
+
</hfoptions>
|
| 131 |
+
|
| 132 |
+
## What You Get
|
| 133 |
+
|
| 134 |
+
**Example output:**
|
| 135 |
+
```text
|
| 136 |
+
[HIGH] DPO loss stuck at ~0.693 (random chance). Model may not be learning preferences.
|
| 137 |
+
Ref: Rafailov et al. (2023) 'DPO', Section 4.2
|
| 138 |
+
|
| 139 |
+
[RECOMMENDED] Increase learning rate 2-5x, check data quality, or reduce beta.
|
| 140 |
+
```
|
| 141 |
+
|
| 142 |
+
## Example Demo
|
| 143 |
+
|
| 144 |
+
See a full working example with auto-stop in action:
|
| 145 |
+
|
| 146 |
+
📂 **[demo/live_demo.ipynb](https://github.com/microsoft/post-training-toolkit/blob/main/demo/notebooks/demo_live_output.ipynb)**
|
| 147 |
+
|
| 148 |
+
📂 **[demo/scripts/custom_heuristic.py](https://github.com/microsoft/post-training-toolkit/blob/main/demo/scripts/custom_heuristic_demo.py)**
|
| 149 |
+
|
| 150 |
+
|
| 151 |
+
### 1. Auto-Metrics
|
| 152 |
+
The callback automatically captures algorithm-specific metrics, backed by the latest research and industry push:
|
| 153 |
+
|
| 154 |
+
| Trainer | Key Metrics Captured |
|
| 155 |
+
|---------|---------------------|
|
| 156 |
+
| **DPO** | loss, win_rate, reward_margin, logps_chosen/rejected |
|
| 157 |
+
| **PPO** | policy_loss, value_loss, entropy, clip_fraction, KL |
|
| 158 |
+
| **GRPO** | group rewards, advantages, policy loss, KL |
|
| 159 |
+
| **SFT** | loss, perplexity, accuracy |
|
| 160 |
+
| **ORPO** | sft_loss, odds_ratio_loss, log_odds_ratio |
|
| 161 |
+
| **KTO** | kl, logps for desirable/undesirable |
|
| 162 |
+
|
| 163 |
+
|
| 164 |
+
### 2. Crash Postmortems
|
| 165 |
+
If training crashes or gets interrupted, you get a `postmortem.json` with full context:
|
| 166 |
+
|
| 167 |
+
```json
|
| 168 |
+
{
|
| 169 |
+
"exit_reason": "exception",
|
| 170 |
+
"last_step": 847,
|
| 171 |
+
"timestamp": "2025-12-17T19:26:04Z",
|
| 172 |
+
"final_metrics": {"dpo_loss": 0.693, "win_rate": 0.52}
|
| 173 |
+
}
|
| 174 |
+
```
|
| 175 |
+
|
| 176 |
+
No more "what step did it die on?"
|
| 177 |
+
|
| 178 |
+
### 3. Auto-Stop on Critical Issues
|
| 179 |
+
|
| 180 |
+
Enable automatic training termination when critical issues are detected:
|
| 181 |
+
|
| 182 |
+
```python
|
| 183 |
+
callback = DiagnosticsCallback(stop_on_critical=True)
|
| 184 |
+
```
|
| 185 |
+
|
| 186 |
+
## Distributed Training
|
| 187 |
+
Works automatically with multi-GPU setups. Zero configuration needed:
|
| 188 |
+
|
| 189 |
+
```bash
|
| 190 |
+
accelerate launch --num_processes 8 train.py
|
| 191 |
+
```
|
| 192 |
+
|
| 193 |
+
Automatically detects stragglers, aggregates metrics across ranks, and tracks memory balance.
|
tasks/tasksmith-1c108f674e97/tests/source/docs/source/quickstart.md
ADDED
|
@@ -0,0 +1,139 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Quickstart
|
| 2 |
+
|
| 3 |
+
TRL is a comprehensive library for post-training foundation models using techniques like Supervised Fine-Tuning (SFT), Group Relative Policy Optimization (GRPO), Direct Preference Optimization (DPO).
|
| 4 |
+
|
| 5 |
+
## Quick Examples
|
| 6 |
+
|
| 7 |
+
Get started instantly with TRL's most popular trainers. Each example uses compact models for quick experimentation.
|
| 8 |
+
|
| 9 |
+
### Supervised Fine-Tuning
|
| 10 |
+
|
| 11 |
+
```python
|
| 12 |
+
from trl import SFTTrainer
|
| 13 |
+
from datasets import load_dataset
|
| 14 |
+
|
| 15 |
+
trainer = SFTTrainer(
|
| 16 |
+
model="Qwen/Qwen2.5-0.5B",
|
| 17 |
+
train_dataset=load_dataset("trl-lib/Capybara", split="train"),
|
| 18 |
+
)
|
| 19 |
+
trainer.train()
|
| 20 |
+
```
|
| 21 |
+
|
| 22 |
+
### Group Relative Policy Optimization
|
| 23 |
+
|
| 24 |
+
```python
|
| 25 |
+
from trl import GRPOTrainer
|
| 26 |
+
from datasets import load_dataset
|
| 27 |
+
from trl.rewards import accuracy_reward
|
| 28 |
+
|
| 29 |
+
trainer = GRPOTrainer(
|
| 30 |
+
model="Qwen/Qwen2.5-0.5B-Instruct",
|
| 31 |
+
train_dataset=load_dataset("trl-lib/DeepMath-103K", split="train"),
|
| 32 |
+
reward_funcs=accuracy_reward,
|
| 33 |
+
)
|
| 34 |
+
trainer.train()
|
| 35 |
+
```
|
| 36 |
+
|
| 37 |
+
### Direct Preference Optimization
|
| 38 |
+
|
| 39 |
+
```python
|
| 40 |
+
from trl import DPOTrainer
|
| 41 |
+
from datasets import load_dataset
|
| 42 |
+
|
| 43 |
+
trainer = DPOTrainer(
|
| 44 |
+
model="Qwen/Qwen2.5-0.5B-Instruct",
|
| 45 |
+
train_dataset=load_dataset("trl-lib/ultrafeedback_binarized", split="train"),
|
| 46 |
+
)
|
| 47 |
+
trainer.train()
|
| 48 |
+
```
|
| 49 |
+
|
| 50 |
+
### Reward Modeling
|
| 51 |
+
|
| 52 |
+
```python
|
| 53 |
+
from trl import RewardTrainer
|
| 54 |
+
from datasets import load_dataset
|
| 55 |
+
|
| 56 |
+
dataset = load_dataset("trl-lib/ultrafeedback_binarized", split="train")
|
| 57 |
+
|
| 58 |
+
trainer = RewardTrainer(
|
| 59 |
+
model="Qwen/Qwen2.5-0.5B-Instruct",
|
| 60 |
+
train_dataset=dataset,
|
| 61 |
+
)
|
| 62 |
+
trainer.train()
|
| 63 |
+
```
|
| 64 |
+
|
| 65 |
+
## Command Line Interface
|
| 66 |
+
|
| 67 |
+
Skip the code entirely - train directly from your terminal:
|
| 68 |
+
|
| 69 |
+
```bash
|
| 70 |
+
# SFT: Fine-tune on instructions
|
| 71 |
+
trl sft --model_name_or_path Qwen/Qwen2.5-0.5B \
|
| 72 |
+
--dataset_name trl-lib/Capybara
|
| 73 |
+
|
| 74 |
+
# DPO: Align with preferences
|
| 75 |
+
trl dpo --model_name_or_path Qwen/Qwen2.5-0.5B-Instruct \
|
| 76 |
+
--dataset_name trl-lib/ultrafeedback_binarized
|
| 77 |
+
|
| 78 |
+
# Reward: Train a reward model
|
| 79 |
+
trl reward --model_name_or_path Qwen/Qwen2.5-0.5B-Instruct \
|
| 80 |
+
--dataset_name trl-lib/ultrafeedback_binarized
|
| 81 |
+
```
|
| 82 |
+
|
| 83 |
+
## What's Next?
|
| 84 |
+
|
| 85 |
+
### 📚 Learn More
|
| 86 |
+
|
| 87 |
+
- [SFT Trainer](sft_trainer) - Complete SFT guide
|
| 88 |
+
- [DPO Trainer](dpo_trainer) - Preference alignment
|
| 89 |
+
- [GRPO Trainer](grpo_trainer) - Group relative policy optimization
|
| 90 |
+
|
| 91 |
+
### 🚀 Scale Up
|
| 92 |
+
|
| 93 |
+
- [Distributed Training](distributing_training) - Multi-GPU setups
|
| 94 |
+
- [Memory Optimization](reducing_memory_usage) - Efficient training
|
| 95 |
+
- [PEFT Integration](peft_integration) - LoRA and QLoRA
|
| 96 |
+
|
| 97 |
+
### 💡 Examples
|
| 98 |
+
|
| 99 |
+
- [Example Scripts](https://github.com/huggingface/trl/tree/main/examples) - Production-ready code
|
| 100 |
+
- [Community Tutorials](community_tutorials) - External guides
|
| 101 |
+
|
| 102 |
+
## Troubleshooting
|
| 103 |
+
|
| 104 |
+
### Out of Memory?
|
| 105 |
+
|
| 106 |
+
Reduce batch size and enable optimizations:
|
| 107 |
+
|
| 108 |
+
<hfoptions id="batch_size">
|
| 109 |
+
<hfoption id="SFT">
|
| 110 |
+
|
| 111 |
+
```python
|
| 112 |
+
training_args = SFTConfig(
|
| 113 |
+
per_device_train_batch_size=1, # Start small
|
| 114 |
+
gradient_accumulation_steps=8, # Maintain effective batch size
|
| 115 |
+
)
|
| 116 |
+
```
|
| 117 |
+
|
| 118 |
+
</hfoption>
|
| 119 |
+
<hfoption id="DPO">
|
| 120 |
+
|
| 121 |
+
```python
|
| 122 |
+
training_args = DPOConfig(
|
| 123 |
+
per_device_train_batch_size=1, # Start small
|
| 124 |
+
gradient_accumulation_steps=8, # Maintain effective batch size
|
| 125 |
+
)
|
| 126 |
+
```
|
| 127 |
+
|
| 128 |
+
</hfoption>
|
| 129 |
+
</hfoptions>
|
| 130 |
+
|
| 131 |
+
### Loss not decreasing?
|
| 132 |
+
|
| 133 |
+
Try adjusting the learning rate:
|
| 134 |
+
|
| 135 |
+
```python
|
| 136 |
+
training_args = SFTConfig(learning_rate=2e-5) # Good starting point
|
| 137 |
+
```
|
| 138 |
+
|
| 139 |
+
For more help, open an [issue on GitHub](https://github.com/huggingface/trl/issues).
|
tasks/tasksmith-1c108f674e97/tests/source/docs/source/rapidfire_integration.md
ADDED
|
@@ -0,0 +1,473 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# RapidFire AI Integration
|
| 2 |
+
|
| 3 |
+
RapidFire AI is an open-source experiment execution framework that integrates with TRL to turn "train one configuration at a time" into **real-time, side-by-side comparison of many configurations on the same GPU(s)** — so you can iterate on hyperparameters, LoRA settings, prompt schemes, and ablations **16–24× faster with no extra hardware**.
|
| 4 |
+
|
| 5 |
+
Links: [GitHub](https://github.com/RapidFireAI/rapidfireai) · [Docs](https://oss-docs.rapidfire.ai) · [Try in Colab](http://tinyurl.com/rapidfireai-colab)
|
| 6 |
+
|
| 7 |
+
## Why use RapidFire AI with TRL?
|
| 8 |
+
|
| 9 |
+
When fine-tuning or post-training with TRL, you typically need to:
|
| 10 |
+
|
| 11 |
+
- Try different hyperparameter configurations
|
| 12 |
+
- Compare different LoRA settings
|
| 13 |
+
- Test different prompt schemes
|
| 14 |
+
- Run ablation studies
|
| 15 |
+
|
| 16 |
+
| Scenario: comparing N training configs on the same GPU(s) | TRL alone | TRL + RapidFire AI |
|
| 17 |
+
| --- | --- | --- |
|
| 18 |
+
| Training strategy | Run N configs sequentially | Run N configs concurrently |
|
| 19 |
+
| When can you compare configs? | After all runs finish | Live, from the first chunk |
|
| 20 |
+
| Stop losers / clone winners mid-training | No | Yes (Interactive Control Operations) |
|
| 21 |
+
|
| 22 |
+
### How It Works
|
| 23 |
+
|
| 24 |
+
RapidFire AI employs **adaptive chunk-based scheduling**:
|
| 25 |
+
|
| 26 |
+
```
|
| 27 |
+
GPU Timeline (Single GPU):
|
| 28 |
+
Chunk 1: [Config A] → [Config B] → [Config C] → [Config D]
|
| 29 |
+
Chunk 2: [Config A] → [Config B] → [Config C] → [Config D]
|
| 30 |
+
Chunk 3: [Config A] → [Config B] → [Config C] → [Config D]
|
| 31 |
+
```
|
| 32 |
+
|
| 33 |
+
This enables:
|
| 34 |
+
|
| 35 |
+
- Early comparison of configurations on same data subsets incrementally
|
| 36 |
+
- Efficient GPU utilization and minimizing idle times
|
| 37 |
+
- Real-time and automated experiment metrics tracking
|
| 38 |
+
- Dynamic control over runs in flight to incentivize more experimentation
|
| 39 |
+
|
| 40 |
+
## Key Features
|
| 41 |
+
|
| 42 |
+
- **16-24× higher experimentation throughput** compared to sequential training.
|
| 43 |
+
- **Almost no code changes** - simple drop-in config APIs that just wrap around existing TRL and PEFT config APIs.
|
| 44 |
+
- **Interactive Control Operations** - real-time control to stop, resume, and clone-modify (with or without warm starting) training runs in flight.
|
| 45 |
+
- **Integration with Fully Sharded Data Parallel (FSDP)** for training large models that do not fit on a single GPU by sharding parameters, gradients, and optimizer states across multiple GPUs.
|
| 46 |
+
- **Full compatibility** with transformers, PEFT, SFTTrainer, DPOTrainer, and GRPOTrainer.
|
| 47 |
+
- **Pluggable experiment tracking**: MLflow (default), TensorBoard, and Trackio, enabled individually or in combination.
|
| 48 |
+
- **Zero-setup Google Colab support**: one-click tutorial notebooks for SFT, DPO, and GRPO on free T4 GPUs.
|
| 49 |
+
- **Production-Ready**: Already used in production environments with complete working examples.
|
| 50 |
+
|
| 51 |
+
## Installation
|
| 52 |
+
|
| 53 |
+
### Prerequisites
|
| 54 |
+
|
| 55 |
+
- Python 3.12.x
|
| 56 |
+
- NVIDIA GPU with Compute Capability 7.x or 8.x (multiple GPUs required for FSDP)
|
| 57 |
+
- CUDA Toolkit 11.8+
|
| 58 |
+
- PyTorch 2.8+
|
| 59 |
+
|
| 60 |
+
### pip install
|
| 61 |
+
|
| 62 |
+
```bash
|
| 63 |
+
pip install rapidfireai
|
| 64 |
+
```
|
| 65 |
+
|
| 66 |
+
Once installed, authenticate with Hugging Face and initialize RapidFire AI:
|
| 67 |
+
|
| 68 |
+
```bash
|
| 69 |
+
# Authenticate with Hugging Face
|
| 70 |
+
hf auth login --token YOUR_TOKEN
|
| 71 |
+
|
| 72 |
+
# Workaround for current issue: https://github.com/huggingface/xet-core/issues/527
|
| 73 |
+
pip uninstall -y hf-xet
|
| 74 |
+
|
| 75 |
+
# Initialize RapidFire AI
|
| 76 |
+
rapidfireai init
|
| 77 |
+
|
| 78 |
+
# Start the RapidFire AI server
|
| 79 |
+
rapidfireai start
|
| 80 |
+
```
|
| 81 |
+
|
| 82 |
+
The dashboard will be available at `http://localhost:8853` where you can monitor and control experiments in real-time.
|
| 83 |
+
|
| 84 |
+
## Quick Start: SFT Training with Multiple Configs
|
| 85 |
+
|
| 86 |
+
Here's a complete example showing how to train multiple SFT configurations concurrently:
|
| 87 |
+
|
| 88 |
+
```python
|
| 89 |
+
from rapidfireai import Experiment
|
| 90 |
+
from rapidfireai.automl import List, RFGridSearch, RFModelConfig, RFLoraConfig, RFSFTConfig
|
| 91 |
+
from datasets import load_dataset
|
| 92 |
+
from transformers import AutoModelForCausalLM, AutoTokenizer
|
| 93 |
+
|
| 94 |
+
# Load dataset
|
| 95 |
+
dataset = load_dataset("bitext/Bitext-customer-support-llm-chatbot-training-dataset")
|
| 96 |
+
train_dataset = dataset["train"].select(range(128)).shuffle(seed=42)
|
| 97 |
+
eval_dataset = dataset["train"].select(range(100, 124)).shuffle(seed=42)
|
| 98 |
+
|
| 99 |
+
# Define data formatting function
|
| 100 |
+
def formatting_function(row):
|
| 101 |
+
return {
|
| 102 |
+
"prompt": [
|
| 103 |
+
{"role": "system", "content": "You are a helpful customer support assistant."},
|
| 104 |
+
{"role": "user", "content": row["instruction"]},
|
| 105 |
+
],
|
| 106 |
+
"completion": [
|
| 107 |
+
{"role": "assistant", "content": row["response"]}
|
| 108 |
+
]
|
| 109 |
+
}
|
| 110 |
+
|
| 111 |
+
# Initialize experiment
|
| 112 |
+
experiment = Experiment(experiment_name="sft-customer-support")
|
| 113 |
+
|
| 114 |
+
# Define multiple LoRA configurations to compare
|
| 115 |
+
peft_configs = List([
|
| 116 |
+
RFLoraConfig(r=8, lora_alpha=16, lora_dropout=0.1,
|
| 117 |
+
target_modules=["q_proj", "v_proj"], bias="none"),
|
| 118 |
+
RFLoraConfig(r=32, lora_alpha=64, lora_dropout=0.1,
|
| 119 |
+
target_modules=["q_proj", "k_proj", "v_proj", "o_proj"], bias="none")
|
| 120 |
+
])
|
| 121 |
+
|
| 122 |
+
# Define multiple training configurations
|
| 123 |
+
# 2 base configs × 2 PEFT configs = 4 total training runs
|
| 124 |
+
config_set = List([
|
| 125 |
+
RFModelConfig(
|
| 126 |
+
model_name="TinyLlama/TinyLlama-1.1B-Chat-v1.0",
|
| 127 |
+
peft_config=peft_configs,
|
| 128 |
+
training_args=RFSFTConfig( # Wraps TRL's SFTConfig
|
| 129 |
+
learning_rate=1e-3,
|
| 130 |
+
per_device_train_batch_size=4,
|
| 131 |
+
max_steps=128,
|
| 132 |
+
fp16=True,
|
| 133 |
+
),
|
| 134 |
+
model_type="causal_lm",
|
| 135 |
+
model_kwargs={"device_map": "auto", "torch_dtype": "auto", "use_cache": False},
|
| 136 |
+
formatting_func=formatting_function,
|
| 137 |
+
),
|
| 138 |
+
RFModelConfig(
|
| 139 |
+
model_name="TinyLlama/TinyLlama-1.1B-Chat-v1.0",
|
| 140 |
+
peft_config=peft_configs,
|
| 141 |
+
training_args=RFSFTConfig(
|
| 142 |
+
learning_rate=1e-4, # Different learning rate
|
| 143 |
+
per_device_train_batch_size=4,
|
| 144 |
+
max_steps=128,
|
| 145 |
+
fp16=True,
|
| 146 |
+
),
|
| 147 |
+
model_type="causal_lm",
|
| 148 |
+
model_kwargs={"device_map": "auto", "torch_dtype": "auto", "use_cache": False},
|
| 149 |
+
formatting_func=formatting_function,
|
| 150 |
+
)
|
| 151 |
+
])
|
| 152 |
+
|
| 153 |
+
# Define model creation function
|
| 154 |
+
def create_model(model_config):
|
| 155 |
+
model = AutoModelForCausalLM.from_pretrained(
|
| 156 |
+
model_config["model_name"],
|
| 157 |
+
**model_config["model_kwargs"]
|
| 158 |
+
)
|
| 159 |
+
tokenizer = AutoTokenizer.from_pretrained(model_config["model_name"])
|
| 160 |
+
return (model, tokenizer)
|
| 161 |
+
|
| 162 |
+
# Create grid search over all configurations
|
| 163 |
+
config_group = RFGridSearch(configs=config_set, trainer_type="SFT")
|
| 164 |
+
|
| 165 |
+
# Run all 4 configurations concurrently with chunk-based scheduling
|
| 166 |
+
experiment.run_fit(config_group, create_model, train_dataset, eval_dataset,
|
| 167 |
+
num_chunks=4, seed=42)
|
| 168 |
+
|
| 169 |
+
# End experiment
|
| 170 |
+
experiment.end()
|
| 171 |
+
```
|
| 172 |
+
|
| 173 |
+
### What Happens During Execution
|
| 174 |
+
|
| 175 |
+
When you run this example:
|
| 176 |
+
|
| 177 |
+
1. **Config Expansion**: 2 base configurations × 2 PEFT configs = 4 total training runs
|
| 178 |
+
2. **Chunk-based Scheduling**: Training data is divided into chunks, and all 4 configs train concurrently
|
| 179 |
+
3. **GPU Swapping**: Models are swapped in/out of GPU memory based on chunk boundaries
|
| 180 |
+
4. **Real-time Tracking**: All metrics visible in the dashboard at `http://localhost:8853`
|
| 181 |
+
5. **Interactive Control**: Stop, resume, or clone-modify any configuration from the dashboard
|
| 182 |
+
|
| 183 |
+
This delivers **16-24× higher throughput** compared to training each configuration sequentially!
|
| 184 |
+
|
| 185 |
+
## Supported TRL Trainers
|
| 186 |
+
|
| 187 |
+
### SFTTrainer
|
| 188 |
+
|
| 189 |
+
Use `RFSFTConfig` as a drop-in replacement for `SFTConfig`:
|
| 190 |
+
|
| 191 |
+
```python
|
| 192 |
+
from rapidfireai.automl import RFSFTConfig
|
| 193 |
+
|
| 194 |
+
training_args = RFSFTConfig(
|
| 195 |
+
learning_rate=5e-5,
|
| 196 |
+
per_device_train_batch_size=4,
|
| 197 |
+
num_train_epochs=3,
|
| 198 |
+
max_length = 512,
|
| 199 |
+
# ... all other SFTConfig parameters supported
|
| 200 |
+
)
|
| 201 |
+
```
|
| 202 |
+
|
| 203 |
+
**Example Notebook**: [SFT for Customer Support](https://github.com/RapidFireAI/rapidfireai/blob/main/tutorial_notebooks/fine-tuning/rf-tutorial-sft-chatqa-lite.ipynb)
|
| 204 |
+
|
| 205 |
+
### DPOTrainer
|
| 206 |
+
|
| 207 |
+
Use `RFDPOConfig` as a drop-in replacement for `DPOConfig`:
|
| 208 |
+
|
| 209 |
+
```python
|
| 210 |
+
from rapidfireai.automl import RFDPOConfig
|
| 211 |
+
|
| 212 |
+
training_args = RFDPOConfig(
|
| 213 |
+
beta=0.1,
|
| 214 |
+
loss_type="sigmoid",
|
| 215 |
+
max_length=1024,
|
| 216 |
+
learning_rate=5e-4,
|
| 217 |
+
# ... all other DPOConfig parameters supported
|
| 218 |
+
)
|
| 219 |
+
```
|
| 220 |
+
|
| 221 |
+
**Example Notebook**: [DPO for Preference Alignment](https://github.com/RapidFireAI/rapidfireai/blob/main/tutorial_notebooks/post-training/rf-tutorial-dpo-alignment-lite.ipynb)
|
| 222 |
+
|
| 223 |
+
### GRPOTrainer
|
| 224 |
+
|
| 225 |
+
Use `RFGRPOConfig` as a drop-in replacement for `GRPOConfig`:
|
| 226 |
+
|
| 227 |
+
```python
|
| 228 |
+
from rapidfireai.automl import RFGRPOConfig
|
| 229 |
+
|
| 230 |
+
training_args = RFGRPOConfig(
|
| 231 |
+
learning_rate=5e-6,
|
| 232 |
+
num_generations=8,
|
| 233 |
+
max_completion_length=256,
|
| 234 |
+
# ... all other GRPOConfig parameters supported
|
| 235 |
+
)
|
| 236 |
+
```
|
| 237 |
+
|
| 238 |
+
**Example Notebook**: [GRPO for Math Reasoning](https://github.com/RapidFireAI/rapidfireai/blob/main/tutorial_notebooks/post-training/rf-tutorial-grpo-mathreasoning-lite.ipynb)
|
| 239 |
+
|
| 240 |
+
## Core Concepts
|
| 241 |
+
|
| 242 |
+
### Chunk-Based Concurrent Training
|
| 243 |
+
|
| 244 |
+
RapidFire AI divides training data into chunks and alternates between configurations:
|
| 245 |
+
|
| 246 |
+
```
|
| 247 |
+
GPU Timeline (Single GPU):
|
| 248 |
+
Chunk 1: [Config A] → [Config B] → [Config C] → [Config D]
|
| 249 |
+
Chunk 2: [Config A] → [Config B] → [Config C] → [Config D]
|
| 250 |
+
Chunk 3: [Config A] → [Config B] → [Config C] → [Config D]
|
| 251 |
+
...
|
| 252 |
+
```
|
| 253 |
+
|
| 254 |
+
This approach maximizes GPU utilization and enables early comparison of configurations while maintaining training stability through automatic checkpointing.
|
| 255 |
+
|
| 256 |
+
### Interactive Control Operations (IC Ops)
|
| 257 |
+
|
| 258 |
+
Through the RapidFire AI dashboard, you can dynamically control running experiments:
|
| 259 |
+
|
| 260 |
+
- **Stop**: Pause a configuration (checkpointed automatically)
|
| 261 |
+
- **Resume**: Continue from last checkpoint
|
| 262 |
+
- **Clone-Modify**: Duplicate a configuration with modifications (new run starts from scratch)
|
| 263 |
+
- **Clone-Modify with Warm Start**: Clone-modify and initialize from the parent's weights
|
| 264 |
+
- **Delete**: Remove failed or unwanted runs
|
| 265 |
+
|
| 266 |
+
This enables adaptive experimentation where you can stop underperforming configs early and clone promising ones with tweaked hyperparameters.
|
| 267 |
+
|
| 268 |
+
### Multi-Config Experimentation
|
| 269 |
+
|
| 270 |
+
Use `RFGridSearch` or `RFRandomSearch` to automatically generate configuration combinations:
|
| 271 |
+
|
| 272 |
+
```python
|
| 273 |
+
# Grid search: tests all combinations
|
| 274 |
+
config_group = RFGridSearch(configs=config_list, trainer_type="SFT")
|
| 275 |
+
|
| 276 |
+
# Random search: samples N configurations
|
| 277 |
+
config_group = RFRandomSearch(configs=config_list, trainer_type="DPO", num_samples=10)
|
| 278 |
+
```
|
| 279 |
+
|
| 280 |
+
## Advanced Features
|
| 281 |
+
|
| 282 |
+
### PEFT/LoRA Integration
|
| 283 |
+
|
| 284 |
+
Full support for parameter-efficient fine-tuning:
|
| 285 |
+
|
| 286 |
+
```python
|
| 287 |
+
from rapidfireai.automl import RFLoraConfig
|
| 288 |
+
from peft import TaskType
|
| 289 |
+
|
| 290 |
+
lora_config = RFLoraConfig(
|
| 291 |
+
task_type=TaskType.CAUSAL_LM,
|
| 292 |
+
r=64,
|
| 293 |
+
lora_alpha=64,
|
| 294 |
+
lora_dropout=0.1,
|
| 295 |
+
target_modules=["q_proj", "k_proj", "v_proj", "o_proj"],
|
| 296 |
+
bias="none"
|
| 297 |
+
)
|
| 298 |
+
```
|
| 299 |
+
|
| 300 |
+
### Custom Reward Functions (GRPO)
|
| 301 |
+
|
| 302 |
+
Define multiple reward functions for GRPO training:
|
| 303 |
+
|
| 304 |
+
```python
|
| 305 |
+
def correctness_reward(prompts, completions, answer, **kwargs):
|
| 306 |
+
"""Reward for correct answers"""
|
| 307 |
+
responses = [completion[0]['content'] for completion in completions]
|
| 308 |
+
extracted = [extract_answer(r) for r in responses]
|
| 309 |
+
return [2.0 if r == a else 0.0 for r, a in zip(extracted, answer)]
|
| 310 |
+
|
| 311 |
+
def format_reward(completions, **kwargs):
|
| 312 |
+
"""Reward for proper formatting"""
|
| 313 |
+
import re
|
| 314 |
+
pattern = r"<reasoning>.*?</reasoning>\s*<answer>.*?</answer>"
|
| 315 |
+
responses = [completion[0]["content"] for completion in completions]
|
| 316 |
+
matches = [re.match(pattern, r) for r in responses]
|
| 317 |
+
return [0.5 if match else 0.0 for match in matches]
|
| 318 |
+
|
| 319 |
+
# Use in model config
|
| 320 |
+
config = RFModelConfig(
|
| 321 |
+
reward_funcs=[correctness_reward, format_reward],
|
| 322 |
+
# ... other parameters
|
| 323 |
+
)
|
| 324 |
+
```
|
| 325 |
+
|
| 326 |
+
### Multi-GPU Support
|
| 327 |
+
|
| 328 |
+
RapidFire AI automatically detects and utilizes all available GPUs. By default, the scheduler distributes independent configurations across GPUs (data-parallel across configs), so no special setup is required to run `N` configs on `N` GPUs concurrently.
|
| 329 |
+
|
| 330 |
+
For models that do not fit on a single GPU, RapidFire AI also supports **Fully Sharded Data Parallel (FSDP)** to shard a single configuration across multiple GPUs — see the next section.
|
| 331 |
+
|
| 332 |
+
### Multi-GPU Training with FSDP
|
| 333 |
+
|
| 334 |
+
When a model is too large for a single GPU, enable FSDP directly through the training args of `RFSFTConfig` or `RFDPOConfig` — the same `fsdp` and `fsdp_config` fields exposed by Hugging Face `TrainingArguments`:
|
| 335 |
+
|
| 336 |
+
```python
|
| 337 |
+
from rapidfireai.automl import RFModelConfig, RFSFTConfig, RFLoraConfig
|
| 338 |
+
|
| 339 |
+
model_config = RFModelConfig(
|
| 340 |
+
model_name="meta-llama/Llama-3.1-8B-Instruct",
|
| 341 |
+
peft_config=RFLoraConfig(
|
| 342 |
+
r=16, lora_alpha=32, lora_dropout=0.05,
|
| 343 |
+
target_modules=["q_proj", "k_proj", "v_proj", "o_proj"],
|
| 344 |
+
bias="none",
|
| 345 |
+
),
|
| 346 |
+
training_args=RFSFTConfig(
|
| 347 |
+
learning_rate=2e-4,
|
| 348 |
+
per_device_train_batch_size=1,
|
| 349 |
+
gradient_accumulation_steps=8,
|
| 350 |
+
fsdp="full_shard auto_wrap",
|
| 351 |
+
fsdp_config={
|
| 352 |
+
"sharding_strategy": "FULL_SHARD",
|
| 353 |
+
"auto_wrap_policy": "TRANSFORMER_BASED_WRAP",
|
| 354 |
+
"backward_prefetch": "backward_pre",
|
| 355 |
+
"forward_prefetch": True,
|
| 356 |
+
"use_orig_params": False,
|
| 357 |
+
"cpu_ram_efficient_loading": True,
|
| 358 |
+
"offload_params": True,
|
| 359 |
+
"sync_module_states": True,
|
| 360 |
+
"limit_all_gathers": True,
|
| 361 |
+
},
|
| 362 |
+
),
|
| 363 |
+
model_type="causal_lm",
|
| 364 |
+
model_kwargs={"torch_dtype": "auto"},
|
| 365 |
+
)
|
| 366 |
+
```
|
| 367 |
+
|
| 368 |
+
Key points:
|
| 369 |
+
|
| 370 |
+
- FSDP works transparently with RapidFire AI's chunk-based scheduling, IC Ops (stop / resume / clone-modify with or without warm-starting), and all supported metric tracking backends.
|
| 371 |
+
- FSDP is fully compatible with PEFT / LoRA — LoRA adapter weights are collected efficiently across shards when saving checkpoints.
|
| 372 |
+
- FSDP composes with grid search and random search: each expanded config gets its own sharded training run.
|
| 373 |
+
|
| 374 |
+
**Example Notebooks**:
|
| 375 |
+
- [SFT with FSDP (lite, small model)](https://github.com/RapidFireAI/rapidfireai/blob/main/tutorial_notebooks/fine-tuning/rf-tutorial-sft-chatqa-fsdp-lite.ipynb)
|
| 376 |
+
- [SFT with FSDP (large model)](https://github.com/RapidFireAI/rapidfireai/blob/main/tutorial_notebooks/fine-tuning/rf-tutorial-sft-chatqa-fsdp-large.ipynb)
|
| 377 |
+
- [DPO with FSDP](https://github.com/RapidFireAI/rapidfireai/blob/main/tutorial_notebooks/post-training/rf-tutorial-dpo-alignment-fsdp-lite.ipynb)
|
| 378 |
+
|
| 379 |
+
### Experiment Tracking Backends
|
| 380 |
+
|
| 381 |
+
RapidFire AI supports three metric logging backends that can be used individually or together: **MLflow** (the default for local installs), **TensorBoard** (the default in Google Colab), and **Trackio**.
|
| 382 |
+
|
| 383 |
+
Select one or more backends at server startup with the `--tracking-backends` flag:
|
| 384 |
+
|
| 385 |
+
```bash
|
| 386 |
+
# MLflow only (default on local installs)
|
| 387 |
+
rapidfireai start --tracking-backends mlflow
|
| 388 |
+
|
| 389 |
+
# TensorBoard only
|
| 390 |
+
rapidfireai start --tracking-backends tensorboard
|
| 391 |
+
|
| 392 |
+
# Any combination
|
| 393 |
+
rapidfireai start --tracking-backends mlflow tensorboard trackio
|
| 394 |
+
```
|
| 395 |
+
|
| 396 |
+
Equivalent environment variables are also available:
|
| 397 |
+
|
| 398 |
+
- `RF_MLFLOW_ENABLED` (default `true`, or `false` in Colab)
|
| 399 |
+
- `RF_TENSORBOARD_ENABLED` (default `false`, or `true` in Colab)
|
| 400 |
+
- `RF_TRACKIO_ENABLED` (default `false`)
|
| 401 |
+
|
| 402 |
+
All three backends receive the same metrics (loss, evaluation scores, learning rate, etc.) and respect IC Ops run lifecycle events, so you can use, for example, Trackio for lightweight sharing alongside MLflow for a full local dashboard.
|
| 403 |
+
|
| 404 |
+
### Running in Google Colab
|
| 405 |
+
|
| 406 |
+
RapidFire AI runs on free Google Colab T4 GPUs, with tutorial notebooks for SFT, DPO, GRPO, and RAG / context-engineering workflows. In Colab, TensorBoard is the default tracking backend (MLflow is disabled for simplicity), and the usual `rapidfireai init` / `rapidfireai start` commands run directly from notebook cells — no terminal access required.
|
| 407 |
+
|
| 408 |
+
Get started: [RapidFire AI in Google Colab](http://tinyurl.com/rapidfireai-colab).
|
| 409 |
+
|
| 410 |
+
## Best Practices
|
| 411 |
+
|
| 412 |
+
### Tuning Chunk Granularity
|
| 413 |
+
|
| 414 |
+
The `num_chunks` parameter controls swap frequency:
|
| 415 |
+
|
| 416 |
+
```python
|
| 417 |
+
# Fewer chunks = less overhead, less frequent comparison
|
| 418 |
+
experiment.run_fit(..., num_chunks=2)
|
| 419 |
+
|
| 420 |
+
# More chunks = more overhead, more frequent comparison
|
| 421 |
+
experiment.run_fit(..., num_chunks=16)
|
| 422 |
+
```
|
| 423 |
+
|
| 424 |
+
**Rule of thumb**: Start with `num_chunks=4` and adjust based on dataset size and number of configurations.
|
| 425 |
+
|
| 426 |
+
### Memory Management
|
| 427 |
+
|
| 428 |
+
For large models, use quantization:
|
| 429 |
+
|
| 430 |
+
```python
|
| 431 |
+
from transformers import BitsAndBytesConfig
|
| 432 |
+
import torch
|
| 433 |
+
|
| 434 |
+
bnb_config = BitsAndBytesConfig(
|
| 435 |
+
load_in_4bit=True,
|
| 436 |
+
bnb_4bit_compute_dtype=torch.bfloat16,
|
| 437 |
+
bnb_4bit_use_double_quant=True,
|
| 438 |
+
bnb_4bit_quant_type="nf4",
|
| 439 |
+
)
|
| 440 |
+
|
| 441 |
+
model_kwargs = {
|
| 442 |
+
"quantization_config": bnb_config,
|
| 443 |
+
"device_map": "auto",
|
| 444 |
+
}
|
| 445 |
+
```
|
| 446 |
+
|
| 447 |
+
## Performance Benchmarks
|
| 448 |
+
|
| 449 |
+
Based on internal benchmarks comparing sequential vs. RapidFire AI concurrent training:
|
| 450 |
+
|
| 451 |
+
| Scenario | Sequential Time | RapidFire AI Time | Speedup |
|
| 452 |
+
|----------|----------------|-------------------|---------|
|
| 453 |
+
| 4 configs, 1 GPU | 120 min | 7.5 min | 16× |
|
| 454 |
+
| 8 configs, 1 GPU | 240 min | 12 min | 20× |
|
| 455 |
+
| 4 configs, 2 GPUs | 60 min | 4 min | 15× |
|
| 456 |
+
| 8 configs, 4 GPUs | 60 min | 3 min | 20× |
|
| 457 |
+
|
| 458 |
+
*Benchmarks performed on NVIDIA A100 40GB with TinyLlama-1.1B and Llama-3.2-1B models*
|
| 459 |
+
|
| 460 |
+
## Troubleshooting
|
| 461 |
+
|
| 462 |
+
For troubleshooting guidance, see the [RapidFire AI Troubleshooting Guide](https://oss-docs.rapidfire.ai/en/latest/troubleshooting.html).
|
| 463 |
+
|
| 464 |
+
## Additional Resources
|
| 465 |
+
- **Colab Notebook**: [RapidFire AI in Google Colab](http://tinyurl.com/rapidfireai-colab)
|
| 466 |
+
- **Documentation**: [oss-docs.rapidfire.ai](https://oss-docs.rapidfire.ai)
|
| 467 |
+
- **GitHub**: [RapidFireAI/rapidfireai](https://github.com/RapidFireAI/rapidfireai)
|
| 468 |
+
- **PyPI**: [pypi.org/project/rapidfireai](https://pypi.org/project/rapidfireai/)
|
| 469 |
+
- **Discord**: [Join our Discord](https://discord.gg/6vSTtncKNN)
|
| 470 |
+
- **Tutorial Notebooks**: [GitHub Repository](https://github.com/RapidFireAI/rapidfireai/tree/main/tutorial_notebooks)
|
| 471 |
+
|
| 472 |
+
Learn more about RapidFire AI in their [official repository](https://github.com/RapidFireAI/rapidfireai) and [documentation](https://oss-docs.rapidfire.ai).
|
| 473 |
+
|
tasks/tasksmith-1c108f674e97/tests/source/docs/source/reducing_memory_usage.md
ADDED
|
@@ -0,0 +1,360 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Reducing Memory Usage
|
| 2 |
+
|
| 3 |
+
Training workflows can often be optimized to **reduce memory consumption**, and TRL provides several built-in features to help achieve this.
|
| 4 |
+
|
| 5 |
+
Below, we outline these techniques and recommend experimenting with different combinations to figure out which configuration works best for your specific setup.
|
| 6 |
+
|
| 7 |
+
Each method includes examples for the supported trainers. If you're unsure whether a technique is compatible with your trainer, please take a look at the corresponding trainer documentation.
|
| 8 |
+
|
| 9 |
+
For additional strategies, such as **gradient checkpointing**, which is supported across all trainers, see the [`transformers` performance guide](https://huggingface.co/docs/transformers/perf_train_gpu_one#gradient-checkpointing).
|
| 10 |
+
|
| 11 |
+
## Truncation
|
| 12 |
+
|
| 13 |
+
Sequence lengths in the dataset can vary widely. When data is batched, sequences are padded to match the longest one in the batch, which can cause high memory usage, even if most sequences are relatively short.
|
| 14 |
+
|
| 15 |
+

|
| 16 |
+
|
| 17 |
+
To reduce memory usage, it's important to truncate sequences to a reasonable length. While TRL trainers truncate sequences by default, you may want to adjust the default truncation length to better align with your specific use case.
|
| 18 |
+
|
| 19 |
+
<hfoptions id="truncation">
|
| 20 |
+
<hfoption id="DPO">
|
| 21 |
+
|
| 22 |
+
DPO truncation is controlled via `max_length`, which truncates the combined prompt+completion sequence.
|
| 23 |
+
|
| 24 |
+

|
| 25 |
+
|
| 26 |
+
To set the truncation parameter, use the following code snippet:
|
| 27 |
+
|
| 28 |
+
```python
|
| 29 |
+
from trl import DPOConfig
|
| 30 |
+
|
| 31 |
+
training_args = DPOConfig(..., max_length=...)
|
| 32 |
+
```
|
| 33 |
+
|
| 34 |
+
> [!WARNING]
|
| 35 |
+
> The legacy `max_prompt_length` and `max_completion_length` parameters are now removed; instead, filter or pre-truncate overlong prompts/completions in your dataset before training.
|
| 36 |
+
|
| 37 |
+
</hfoption>
|
| 38 |
+
<hfoption id="SFT">
|
| 39 |
+
|
| 40 |
+
SFT truncation is applied to the input sequence via the `max_length` parameter.
|
| 41 |
+
|
| 42 |
+

|
| 43 |
+
|
| 44 |
+
To set the truncation parameter, use the following code snippet:
|
| 45 |
+
|
| 46 |
+
```python
|
| 47 |
+
from trl import SFTConfig
|
| 48 |
+
|
| 49 |
+
training_args = SFTConfig(..., max_length=...)
|
| 50 |
+
```
|
| 51 |
+
|
| 52 |
+
</hfoption>
|
| 53 |
+
</hfoptions>
|
| 54 |
+
|
| 55 |
+
### How to choose the `max_length` value?
|
| 56 |
+
|
| 57 |
+
If `max_length` is too small, a significant portion of your tokens will be discarded and won't contribute to training. If it's too large, memory usage can spike, potentially leading to out-of-memory (OOM) errors. Without packing or padding-free, a large `max_length` may also result in inefficient training, as many tokens will be padding.
|
| 58 |
+
|
| 59 |
+
To help you choose an appropriate value, we provide a utility to visualize the sequence length distribution in your dataset.
|
| 60 |
+
|
| 61 |
+
<iframe src="https://trl-lib-dataset-length-profiler.hf.space" frameborder="0" width="100%" height="1000"></iframe>
|
| 62 |
+
|
| 63 |
+
## Packing
|
| 64 |
+
|
| 65 |
+
> [!TIP]
|
| 66 |
+
> This technique is available only for **SFT** training and setups that use **FlashAttention** (or its variants).
|
| 67 |
+
|
| 68 |
+
[Truncation](#truncation) has several drawbacks:
|
| 69 |
+
|
| 70 |
+
1. **Loss of information**: Important tokens at the end of sequences may be discarded.
|
| 71 |
+
2. **Choosing truncation length**: Too short loses data; too long reduces efficiency.
|
| 72 |
+
|
| 73 |
+
Packing mitigates these issues by grouping multiple sequences into the same training row, filling each row up to `max_length`.
|
| 74 |
+
|
| 75 |
+

|
| 76 |
+
|
| 77 |
+
TRL implements packing using **Best-Fit Decreasing (BFD)** bin packing, which groups sequences efficiently while minimizing padding. When a sequence exceeds `max_length`, different strategies determine how the overflow tokens are handled.
|
| 78 |
+
|
| 79 |
+
TRL supports three strategies:
|
| 80 |
+
|
| 81 |
+
* `"bfd"` (default): Uses **Best-Fit Decreasing packing**. If a sequence exceeds `max_length`, the overflow tokens are discarded.
|
| 82 |
+
|
| 83 |
+
* `"bfd_split"`: Uses **Best-Fit Decreasing packing**, but long sequences are split into chunks ≤ `max_length` before packing. This preserves all tokens and follows the approach proposed in [Fewer Truncations Improve Language Modeling](https://huggingface.co/papers/2404.10830).
|
| 84 |
+
|
| 85 |
+
* `"wrapped"`: All tokens are concatenated into a stream and split into fixed-length blocks. This minimizes padding but may mix unrelated examples. This strategy corresponds to the *concatenate-then-split* preprocessing described in the literature (e.g., [Fewer Truncations Improve Language Modeling](https://huggingface.co/papers/2404.10830)). It has the downside of breaking sequence continuity for a large fraction of the dataset, which hurts performance, as discussed in the [Qwen3-Coder-Next Technical Report](https://huggingface.co/papers/2603.00729).
|
| 86 |
+
|
| 87 |
+
> [!NOTE]
|
| 88 |
+
> If all sequences are shorter than `max_length`, **`bfd` and `bfd_split` behave identically**, since no truncation or splitting is required.
|
| 89 |
+
|
| 90 |
+
```python
|
| 91 |
+
from trl import SFTConfig
|
| 92 |
+
|
| 93 |
+
training_args = SFTConfig(
|
| 94 |
+
...,
|
| 95 |
+
packing=True,
|
| 96 |
+
packing_strategy="bfd",
|
| 97 |
+
max_length=512,
|
| 98 |
+
)
|
| 99 |
+
```
|
| 100 |
+
|
| 101 |
+
## PEFT for parameter-efficient fine-tuning
|
| 102 |
+
|
| 103 |
+
Parameter-Efficient Fine-Tuning (PEFT) methods like LoRA are among the most effective techniques for reducing memory usage during training. Instead of training all model parameters, PEFT methods train only a small number of adapter parameters, significantly reducing memory requirements and enabling fine-tuning of larger models on limited hardware.
|
| 104 |
+
|
| 105 |
+
For comprehensive details on using PEFT with TRL, including various adapter methods, quantization options, and advanced configurations, see [PEFT Integration](peft_integration).
|
| 106 |
+
|
| 107 |
+
To use PEFT for reducing memory usage:
|
| 108 |
+
|
| 109 |
+
```python
|
| 110 |
+
from datasets import load_dataset
|
| 111 |
+
from peft import LoraConfig
|
| 112 |
+
from trl import SFTTrainer
|
| 113 |
+
|
| 114 |
+
dataset = load_dataset("trl-lib/Capybara", split="train")
|
| 115 |
+
|
| 116 |
+
peft_config = LoraConfig()
|
| 117 |
+
|
| 118 |
+
trainer = SFTTrainer(
|
| 119 |
+
model="Qwen/Qwen2.5-0.5B",
|
| 120 |
+
train_dataset=dataset,
|
| 121 |
+
peft_config=peft_config,
|
| 122 |
+
)
|
| 123 |
+
```
|
| 124 |
+
|
| 125 |
+
PEFT can be combined with other memory reduction techniques such as quantization (4-bit or 8-bit) for even greater memory savings. See [PEFT Integration](peft_integration) for quantization examples.
|
| 126 |
+
|
| 127 |
+
## Liger for reducing peak memory usage
|
| 128 |
+
|
| 129 |
+
[Liger Kernel](https://github.com/linkedin/Liger-Kernel) is a collection of Triton kernels designed specifically for LLM training. It can effectively increase multi-GPU training throughput by 20% and reduce memory usage by 60%.
|
| 130 |
+
|
| 131 |
+
For more information, see [Liger Kernel Integration](liger_kernel_integration).
|
| 132 |
+
|
| 133 |
+
To use Liger for reducing peak memory usage, use the following code snippet:
|
| 134 |
+
|
| 135 |
+
<hfoptions id="liger">
|
| 136 |
+
<hfoption id="SFT">
|
| 137 |
+
|
| 138 |
+
```python
|
| 139 |
+
from trl import SFTConfig
|
| 140 |
+
|
| 141 |
+
training_args = SFTConfig(..., use_liger_kernel=True)
|
| 142 |
+
```
|
| 143 |
+
|
| 144 |
+
</hfoption>
|
| 145 |
+
<hfoption id="DPO">
|
| 146 |
+
|
| 147 |
+
```python
|
| 148 |
+
from trl import DPOConfig
|
| 149 |
+
|
| 150 |
+
training_args = DPOConfig(..., use_liger_kernel=True)
|
| 151 |
+
```
|
| 152 |
+
|
| 153 |
+
</hfoption>
|
| 154 |
+
<hfoption id="GRPO">
|
| 155 |
+
|
| 156 |
+
```python
|
| 157 |
+
from trl import GRPOConfig
|
| 158 |
+
|
| 159 |
+
training_args = GRPOConfig(..., use_liger_kernel=True)
|
| 160 |
+
```
|
| 161 |
+
|
| 162 |
+
</hfoption>
|
| 163 |
+
<hfoption id="KTO">
|
| 164 |
+
|
| 165 |
+
```python
|
| 166 |
+
from trl.experimental.kto import KTOConfig
|
| 167 |
+
|
| 168 |
+
training_args = KTOConfig(..., use_liger_kernel=True)
|
| 169 |
+
```
|
| 170 |
+
|
| 171 |
+
</hfoption>
|
| 172 |
+
<hfoption id="GKD">
|
| 173 |
+
|
| 174 |
+
```python
|
| 175 |
+
from trl.experimental.gkd import GKDConfig
|
| 176 |
+
|
| 177 |
+
training_args = GKDConfig(..., use_liger_kernel=True)
|
| 178 |
+
```
|
| 179 |
+
|
| 180 |
+
</hfoption>
|
| 181 |
+
</hfoptions>
|
| 182 |
+
|
| 183 |
+
## Chunked cross-entropy for reducing peak memory usage
|
| 184 |
+
|
| 185 |
+
At large vocabulary sizes, the `[batch × seq_len × vocab]` logits tensor produced by the LM head is one of the dominant activations held in memory across forward and backward. `loss_type="chunked_nll"` in [`SFTTrainer`] avoids materializing it all at once: positions with `labels == -100` are dropped *before* the `lm_head` matmul, and the cross-entropy is computed in chunks of tokens using gradient checkpointing, so peak activation memory scales with `chunk_size × vocab_size` instead of `(batch × seq_len) × vocab_size`.
|
| 186 |
+
|
| 187 |
+
Same math as the default loss — this is a memory optimization, not a new loss.
|
| 188 |
+
|
| 189 |
+
```python
|
| 190 |
+
from trl import SFTConfig
|
| 191 |
+
|
| 192 |
+
training_args = SFTConfig(..., loss_type="chunked_nll")
|
| 193 |
+
```
|
| 194 |
+
|
| 195 |
+
Expect **typically ~30 % less peak VRAM, up to ~50 %** on large-vocab models (measured on `Qwen3-1.7B`, vocab ≈ 151k — ~30 % on single-GPU, up to ~50 % under FSDP2 × 4 GPUs) with wall time typically neutral or slightly faster. See the [PR #5575](https://github.com/huggingface/trl/pull/5575) for the full benchmark across single-GPU, DDP, FSDP2, packing, long-context, and fp32 configurations.
|
| 196 |
+
Under FSDP2, pass `--fsdp_reshard_after_forward false` to `accelerate launch` — the chunked path otherwise re-gathers `lm_head.weight` per chunk during backward, adding noticeable wall-time.
|
| 197 |
+
|
| 198 |
+
Not compatible with `use_liger_kernel=True`, PEFT, or VLM.
|
| 199 |
+
|
| 200 |
+
## Padding-free
|
| 201 |
+
|
| 202 |
+
Padding-free batching is an alternative approach for reducing memory usage. In this method, a batch is first sampled and then flattened into a single sequence, avoiding padding. Unlike packing, which can result in incomplete sequences by combining parts of different samples, padding-free batching ensures that all sequences remain complete and intact.
|
| 203 |
+
|
| 204 |
+

|
| 205 |
+
|
| 206 |
+
> [!WARNING]
|
| 207 |
+
> It's highly recommended to use padding-free batching with **FlashAttention 2** or **FlashAttention 3**. Otherwise, you may encounter batch contamination issues.
|
| 208 |
+
|
| 209 |
+
<hfoptions id="padding-free">
|
| 210 |
+
<hfoption id="DPO">
|
| 211 |
+
|
| 212 |
+
```python
|
| 213 |
+
from trl import DPOConfig
|
| 214 |
+
|
| 215 |
+
training_args = DPOConfig(..., padding_free=True, model_init_kwargs={"attn_implementation": "kernels-community/flash-attn2"})
|
| 216 |
+
```
|
| 217 |
+
|
| 218 |
+
</hfoption>
|
| 219 |
+
<hfoption id="SFT">
|
| 220 |
+
|
| 221 |
+
```python
|
| 222 |
+
from trl import SFTConfig
|
| 223 |
+
|
| 224 |
+
training_args = SFTConfig(..., padding_free=True, model_init_kwargs={"attn_implementation": "kernels-community/flash-attn2"})
|
| 225 |
+
```
|
| 226 |
+
|
| 227 |
+
</hfoption>
|
| 228 |
+
</hfoptions>
|
| 229 |
+
|
| 230 |
+
## Activation offloading
|
| 231 |
+
|
| 232 |
+
Activation offloading is a memory efficiency technique that reduces GPU VRAM usage by temporarily moving activation tensors to CPU RAM during the forward pass and bringing them back only when needed for the backward pass. This significantly reduces peak memory usage at the cost of slightly increased training time.
|
| 233 |
+
|
| 234 |
+
To enable activation offloading in your SFT training configuration:
|
| 235 |
+
|
| 236 |
+
```python
|
| 237 |
+
from trl import SFTConfig
|
| 238 |
+
|
| 239 |
+
training_args = SFTConfig(..., activation_offloading=True)
|
| 240 |
+
```
|
| 241 |
+
|
| 242 |
+
Under the hood, activation offloading implements PyTorch's [`saved_tensors_hooks`](https://pytorch.org/tutorials/intermediate/autograd_saved_tensors_hooks_tutorial.html#hooks-for-autograd-saved-tensors) to intercept activations during the forward pass. It intelligently manages which tensors to offload based on size and context, avoiding offloading output tensors that would be inefficient. For performance optimization, it can, via a flag (which is true by default), use CUDA streams to overlap computation with CPU-GPU transfers.
|
| 243 |
+
|
| 244 |
+
## Padding Sequences to a Multiple
|
| 245 |
+
|
| 246 |
+
> [!TIP]
|
| 247 |
+
> This technique is supported for **SFT** and **Reward** trainers currently.
|
| 248 |
+
|
| 249 |
+
When enabled, this option ensures that all sequences are **padded to a multiple** of the specified value.
|
| 250 |
+
This can improve computational efficiency on some hardware by aligning sequence lengths to memory-friendly boundaries.
|
| 251 |
+
|
| 252 |
+
<hfoptions id="pad_to_multiple_of">
|
| 253 |
+
<hfoption id="SFT">
|
| 254 |
+
|
| 255 |
+
```python
|
| 256 |
+
from trl import SFTConfig
|
| 257 |
+
|
| 258 |
+
training_args = SFTConfig(..., pad_to_multiple_of=2048)
|
| 259 |
+
```
|
| 260 |
+
|
| 261 |
+
</hfoption>
|
| 262 |
+
<hfoption id="Reward">
|
| 263 |
+
|
| 264 |
+
```python
|
| 265 |
+
from trl import RewardConfig
|
| 266 |
+
|
| 267 |
+
training_args = RewardConfig(..., pad_to_multiple_of=2048)
|
| 268 |
+
```
|
| 269 |
+
|
| 270 |
+
</hfoption>
|
| 271 |
+
</hfoptions>
|
| 272 |
+
|
| 273 |
+
## Disabling model gathering for generation in online methods
|
| 274 |
+
|
| 275 |
+
When using DeepSpeed ZeRO-3, model weights are sharded across multiple GPUs. Online methods involve generating completions from the model as part of the training process. During this step, the model weights are temporarily gathered on a single GPU for generation. For very large models, this gathering can lead to OOM errors, as described in this issue: [#2250](https://github.com/huggingface/trl/issues/2250#issue-2598304204).
|
| 276 |
+
|
| 277 |
+
If you encounter this issue, you can disable the gathering of model weights for generation by setting the following parameter:
|
| 278 |
+
|
| 279 |
+
<hfoptions id="ds3_gather_for_generation">
|
| 280 |
+
<hfoption id="GRPO">
|
| 281 |
+
|
| 282 |
+
```python
|
| 283 |
+
from trl import GRPOConfig
|
| 284 |
+
|
| 285 |
+
training_args = GRPOConfig(..., ds3_gather_for_generation=False)
|
| 286 |
+
```
|
| 287 |
+
|
| 288 |
+
</hfoption>
|
| 289 |
+
<hfoption id="Online DPO">
|
| 290 |
+
|
| 291 |
+
```python
|
| 292 |
+
from trl.experimental.online_dpo import OnlineDPOConfig
|
| 293 |
+
|
| 294 |
+
training_args = OnlineDPOConfig(..., ds3_gather_for_generation=False)
|
| 295 |
+
```
|
| 296 |
+
|
| 297 |
+
</hfoption>
|
| 298 |
+
<hfoption id="PPO">
|
| 299 |
+
|
| 300 |
+
```python
|
| 301 |
+
from trl.experimental.ppo import PPOConfig
|
| 302 |
+
|
| 303 |
+
training_args = PPOConfig(..., ds3_gather_for_generation=False)
|
| 304 |
+
```
|
| 305 |
+
|
| 306 |
+
</hfoption>
|
| 307 |
+
<hfoption id="RLOO">
|
| 308 |
+
|
| 309 |
+
```python
|
| 310 |
+
from trl import RLOOConfig
|
| 311 |
+
|
| 312 |
+
training_args = RLOOConfig(..., ds3_gather_for_generation=False)
|
| 313 |
+
```
|
| 314 |
+
|
| 315 |
+
</hfoption>
|
| 316 |
+
</hfoptions>
|
| 317 |
+
|
| 318 |
+
This adjustment prevents model weights from being gathered, avoiding OOM errors, but it may result in slower generation speeds.
|
| 319 |
+
|
| 320 |
+
## vLLM sleep mode
|
| 321 |
+
|
| 322 |
+
When using **vLLM** as the generation backend for online training methods, you can enable _sleep mode_ to offload vLLM parameters and cache to CPU RAM during the optimization step and reload them back to GPU VRAM when needed for weight synchronization and generation.
|
| 323 |
+
|
| 324 |
+
<hfoptions id="vllm_sleep">
|
| 325 |
+
<hfoption id="GRPO">
|
| 326 |
+
|
| 327 |
+
```python
|
| 328 |
+
from trl import GRPOConfig
|
| 329 |
+
|
| 330 |
+
training_args = GRPOConfig(..., vllm_enable_sleep_mode=True)
|
| 331 |
+
```
|
| 332 |
+
|
| 333 |
+
</hfoption>
|
| 334 |
+
<hfoption id="RLOO">
|
| 335 |
+
|
| 336 |
+
```python
|
| 337 |
+
from trl import RLOOConfig
|
| 338 |
+
|
| 339 |
+
training_args = RLOOConfig(..., vllm_enable_sleep_mode=True)
|
| 340 |
+
```
|
| 341 |
+
|
| 342 |
+
</hfoption>
|
| 343 |
+
</hfoptions>
|
| 344 |
+
|
| 345 |
+
Offloading the vLLM weights and cache helps keep GPU memory usage low, which can be particularly beneficial when training large models or using limited GPU resources. However, waking the vLLM engine from sleep mode introduces some host–device transfer latency, which may slightly impact training speed.
|
| 346 |
+
|
| 347 |
+
## Gradient checkpointing
|
| 348 |
+
|
| 349 |
+
Gradient checkpointing trades compute for memory by not storing all intermediate activations during the forward pass, recomputing them during the backward pass instead.
|
| 350 |
+
|
| 351 |
+
```python
|
| 352 |
+
from trl import SFTConfig
|
| 353 |
+
|
| 354 |
+
training_args = SFTConfig(..., gradient_checkpointing=True)
|
| 355 |
+
```
|
| 356 |
+
|
| 357 |
+
> [!NOTE]
|
| 358 |
+
> Gradient checkpointing is enabled by default in all trainers to optimize memory usage. You can disable it by setting `gradient_checkpointing=False` if needed.
|
| 359 |
+
|
| 360 |
+
For more memory optimization techniques, see the [Transformers Performance Guide](https://huggingface.co/docs/transformers/perf_train_gpu_one#gradient-checkpointing).
|
tasks/tasksmith-1c108f674e97/tests/source/docs/source/reward_trainer.md
ADDED
|
@@ -0,0 +1,234 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Reward Modeling
|
| 2 |
+
|
| 3 |
+
[](https://huggingface.co/models?other=reward-trainer,trl)
|
| 4 |
+
|
| 5 |
+
## Overview
|
| 6 |
+
|
| 7 |
+
TRL supports the Outcome-supervised Reward Modeling (ORM) Trainer for training reward models.
|
| 8 |
+
|
| 9 |
+
This post-training method was contributed by [Younes Belkada](https://huggingface.co/ybelkada).
|
| 10 |
+
|
| 11 |
+
## Quick start
|
| 12 |
+
|
| 13 |
+
This example demonstrates how to train a reward model using the [`RewardTrainer`] from TRL. We train a [Qwen 3 0.6B](https://huggingface.co/Qwen/Qwen3-0.6B) model on the [UltraFeedback dataset](https://huggingface.co/datasets/trl-lib/ultrafeedback_binarized), large-scale, fine-grained, diverse preference dataset.
|
| 14 |
+
|
| 15 |
+
```python
|
| 16 |
+
from trl import RewardTrainer
|
| 17 |
+
from datasets import load_dataset
|
| 18 |
+
|
| 19 |
+
trainer = RewardTrainer(
|
| 20 |
+
model="Qwen/Qwen3-0.6B",
|
| 21 |
+
train_dataset=load_dataset("trl-lib/ultrafeedback_binarized", split="train"),
|
| 22 |
+
)
|
| 23 |
+
trainer.train()
|
| 24 |
+
```
|
| 25 |
+
|
| 26 |
+
<iframe src="https://trl-lib-trackio.hf.space/?project=trl-documentation&metrics=train*&sidebar=hidden&runs=reward_qwen3-0.6B_ultrafeedback2" style="width: 100%; min-width: 300px; max-width: 800px;" height="830" frameBorder="0"></iframe>
|
| 27 |
+
|
| 28 |
+
## Expected dataset type and format
|
| 29 |
+
|
| 30 |
+
[`RewardTrainer`] supports [preference](dataset_formats#preference) datasets type (both implicit and explicit prompt). The [`RewardTrainer`] is compatible with both [standard](dataset_formats#standard) and [conversational](dataset_formats#conversational) dataset formats. When provided with a conversational dataset, the trainer will automatically apply the chat template to the dataset.
|
| 31 |
+
|
| 32 |
+
```python
|
| 33 |
+
# Standard preference (implicit prompt)
|
| 34 |
+
{"chosen": "The sky is blue.",
|
| 35 |
+
"rejected": "The sky is green."}
|
| 36 |
+
|
| 37 |
+
# Conversational preference (implicit prompt)
|
| 38 |
+
{"chosen": [{"role": "user", "content": "What color is the sky?"},
|
| 39 |
+
{"role": "assistant", "content": "It is blue."}],
|
| 40 |
+
"rejected": [{"role": "user", "content": "What color is the sky?"},
|
| 41 |
+
{"role": "assistant", "content": "It is green."}]}
|
| 42 |
+
|
| 43 |
+
# Standard preference (explicit prompt)
|
| 44 |
+
{"prompt": "The sky is",
|
| 45 |
+
"chosen": " blue.",
|
| 46 |
+
"rejected": " green."}
|
| 47 |
+
|
| 48 |
+
# Conversational preference (explicit prompt)
|
| 49 |
+
{"prompt": [{"role": "user", "content": "What color is the sky?"}],
|
| 50 |
+
"chosen": [{"role": "assistant", "content": "It is blue."}],
|
| 51 |
+
"rejected": [{"role": "assistant", "content": "It is green."}]}
|
| 52 |
+
```
|
| 53 |
+
|
| 54 |
+
If your dataset is not in one of these formats, you can preprocess it to convert it into the expected format. Here is an example with the [lmarena-ai/arena-human-preference-55k](https://huggingface.co/datasets/lmarena-ai/arena-human-preference-55k) dataset:
|
| 55 |
+
|
| 56 |
+
```python
|
| 57 |
+
from datasets import load_dataset
|
| 58 |
+
import json
|
| 59 |
+
|
| 60 |
+
dataset = load_dataset("lmarena-ai/arena-human-preference-55k")
|
| 61 |
+
|
| 62 |
+
# Filter out ties
|
| 63 |
+
dataset = dataset.filter(lambda example: example["winner_tie"] == 0)
|
| 64 |
+
|
| 65 |
+
# Create 'chosen' and 'rejected' fields based on the winner column
|
| 66 |
+
def response_a_b_to_chosen_rejected(example):
|
| 67 |
+
if example["winner_model_a"] == 1:
|
| 68 |
+
example["chosen"] = example["response_a"]
|
| 69 |
+
example["rejected"] = example["response_b"]
|
| 70 |
+
else:
|
| 71 |
+
example["chosen"] = example["response_b"]
|
| 72 |
+
example["rejected"] = example["response_a"]
|
| 73 |
+
return example
|
| 74 |
+
|
| 75 |
+
dataset = dataset.map(response_a_b_to_chosen_rejected)
|
| 76 |
+
|
| 77 |
+
# Convert to conversational format
|
| 78 |
+
def make_conversation(example):
|
| 79 |
+
prompt = json.loads(example["prompt"])[0] # '["What color is the sky?"]' -> "What color is the sky?"
|
| 80 |
+
chosen = json.loads(example["chosen"])[0]
|
| 81 |
+
rejected = json.loads(example["rejected"])[0]
|
| 82 |
+
return {
|
| 83 |
+
"chosen": [{"role": "user", "content": prompt}, {"role": "assistant", "content": chosen}],
|
| 84 |
+
"rejected": [{"role": "user", "content": prompt}, {"role": "assistant", "content": rejected}],
|
| 85 |
+
}
|
| 86 |
+
|
| 87 |
+
|
| 88 |
+
dataset = dataset.map(make_conversation)
|
| 89 |
+
|
| 90 |
+
# Keep only necessary columns
|
| 91 |
+
dataset = dataset.select_columns(["chosen", "rejected"])
|
| 92 |
+
|
| 93 |
+
print(next(iter(dataset["train"])))
|
| 94 |
+
```
|
| 95 |
+
|
| 96 |
+
```json
|
| 97 |
+
{
|
| 98 |
+
"chosen": [
|
| 99 |
+
{"role": "user", "content": "Is it morally right to try to have a certain percentage of females on managerial positions?"},
|
| 100 |
+
{"role": "assistant", "content": "The question of whether it is morally right to aim for a certain percentage of females..."},
|
| 101 |
+
],
|
| 102 |
+
"rejected": [
|
| 103 |
+
{"role": "user", "content": "Is it morally right to try to have a certain percentage of females on managerial positions?"},
|
| 104 |
+
{"role": "assistant", "content": "As an AI, I don't have personal beliefs or opinions. However, ..."},
|
| 105 |
+
],
|
| 106 |
+
}
|
| 107 |
+
```
|
| 108 |
+
|
| 109 |
+
## Looking deeper into the training method
|
| 110 |
+
|
| 111 |
+
Reward Models (RMs) are typically trained using supervised learning on datasets containing pairs of preferred and non-preferred responses. The goal is to learn a function that assigns higher scores to preferred responses, enabling the model to rank outputs based on preferences.
|
| 112 |
+
|
| 113 |
+
This section breaks down how reward modeling works in practice, covering the key steps: **preprocessing** and **loss computation**.
|
| 114 |
+
|
| 115 |
+
### Preprocessing and tokenization
|
| 116 |
+
|
| 117 |
+
During training, each example is expected to contain a **chosen** and **rejected** field. For more details on the expected formats, see [Dataset formats - Preference](dataset_formats#preference).
|
| 118 |
+
The [`RewardTrainer`] tokenizes each input using the model's tokenizer. If prompts and completions (chosen and rejected) are provided separately (explicit prompt case), they are concatenated before tokenization.
|
| 119 |
+
|
| 120 |
+
### Computing the loss
|
| 121 |
+
|
| 122 |
+
Let \\( x \\) be the input sequence (prompt) and \\( y^+ \\) and \\( y^- \\) be the chosen and rejected sequences respectively. Under the Bradley-Terry model ([Bradley & Terry, 1952](https://www.jstor.org/stable/2334029)), the probability that \\( y^+ \\) is preferred over \\( y^- \\) given a reward function \\( r \\) is \\( p(y^+ ≻ y^- |x) = \sigma(r(x, y^+)−r(x, y^-)) \\), where \\( σ \\) is the sigmoid function.
|
| 123 |
+
|
| 124 |
+
The reward model \\( r_\theta(x, y) \\) is trained to assign higher scores to preferred responses \\( y^+ \\) over non-preferred ones \\( y^- \\). The loss is then defined as the negative log-likelihood of the observed preferences:
|
| 125 |
+
|
| 126 |
+
$$
|
| 127 |
+
\mathcal{L}(\theta) = - \mathbb{E}_{(x,y^+,y^-) \sim \mathcal{D}} \left[ \log \sigma(r_\theta(x, y^+) - r_\theta(x, y^-)) \right].
|
| 128 |
+
$$
|
| 129 |
+
|
| 130 |
+
> [!TIP]
|
| 131 |
+
> The Bradley-Terry model is underdetermined, meaning that adding a constant to all rewards does not change the preference probabilities. To address this, [Helping or Herding? Reward Model Ensembles Mitigate but do not Eliminate Reward Hacking](https://huggingface.co/papers/2312.09244) proposes adding an auxiliary loss term that encourages the rewards to be centered around zero. This is controlled by the `center_rewards_coefficient` parameter in the [`RewardConfig`]. The recommended value is `1e-2`.
|
| 132 |
+
|
| 133 |
+
## Logged metrics
|
| 134 |
+
|
| 135 |
+
While training and evaluating we record the following reward metrics:
|
| 136 |
+
|
| 137 |
+
* `global_step`: The total number of optimizer steps taken so far.
|
| 138 |
+
* `epoch`: The current epoch number, based on dataset iteration.
|
| 139 |
+
* `num_tokens`: The total number of tokens processed so far.
|
| 140 |
+
* `loss`: The average loss over the last logging interval.
|
| 141 |
+
* `accuracy`: The proportion of correct predictions (i.e., the model assigned a higher score to the chosen response than to the rejected one) averaged over the last logging interval.
|
| 142 |
+
* `min_reward`: The minimum reward score assigned by the model. This value is averaged over the logging interval.
|
| 143 |
+
* `mean_reward`: The average reward score assigned by the model over the last logging interval.
|
| 144 |
+
* `max_reward`: The maximum reward score assigned by the model. This value is averaged over the logging interval.
|
| 145 |
+
* `margin`: The average margin (difference between chosen and rejected rewards) over the last logging interval.
|
| 146 |
+
* `learning_rate`: The current learning rate, which may change dynamically if a scheduler is used.
|
| 147 |
+
* `grad_norm`: The L2 norm of the gradients, computed before gradient clipping.
|
| 148 |
+
|
| 149 |
+
## Customization
|
| 150 |
+
|
| 151 |
+
### Model initialization
|
| 152 |
+
|
| 153 |
+
You can directly pass the kwargs of the [`~transformers.AutoModelForSequenceClassification.from_pretrained()`] method to the [`RewardConfig`]. For example, if you want to load a model in a different precision, analogous to
|
| 154 |
+
|
| 155 |
+
```python
|
| 156 |
+
model = AutoModelForSequenceClassification.from_pretrained("Qwen/Qwen3-0.6B", dtype=torch.bfloat16)
|
| 157 |
+
```
|
| 158 |
+
|
| 159 |
+
you can do so by passing the `model_init_kwargs={"dtype": torch.bfloat16}` argument to the [`RewardConfig`].
|
| 160 |
+
|
| 161 |
+
```python
|
| 162 |
+
from trl import RewardConfig
|
| 163 |
+
|
| 164 |
+
training_args = RewardConfig(
|
| 165 |
+
model_init_kwargs={"dtype": torch.bfloat16},
|
| 166 |
+
)
|
| 167 |
+
```
|
| 168 |
+
|
| 169 |
+
Note that all keyword arguments of [`~transformers.AutoModelForSequenceClassification.from_pretrained()`] are supported, except for `num_labels`, which is automatically set to 1.
|
| 170 |
+
|
| 171 |
+
### Train adapters with PEFT
|
| 172 |
+
|
| 173 |
+
We support tight integration with 🤗 PEFT library, allowing any user to conveniently train adapters and share them on the Hub, rather than training the entire model.
|
| 174 |
+
|
| 175 |
+
```python
|
| 176 |
+
from datasets import load_dataset
|
| 177 |
+
from trl import RewardTrainer
|
| 178 |
+
from peft import LoraConfig
|
| 179 |
+
|
| 180 |
+
dataset = load_dataset("trl-lib/ultrafeedback_binarized", split="train")
|
| 181 |
+
|
| 182 |
+
trainer = RewardTrainer(
|
| 183 |
+
"Qwen/Qwen3-4B",
|
| 184 |
+
train_dataset=dataset,
|
| 185 |
+
peft_config=LoraConfig(modules_to_save=["score"]) # important to include the score head when base model is not a sequence classification model
|
| 186 |
+
)
|
| 187 |
+
|
| 188 |
+
trainer.train()
|
| 189 |
+
```
|
| 190 |
+
|
| 191 |
+
You can also continue training your [`~peft.PeftModel`]. For that, first load a `PeftModel` outside [`RewardTrainer`] and pass it directly to the trainer without the `peft_config` argument being passed.
|
| 192 |
+
|
| 193 |
+
```python
|
| 194 |
+
from datasets import load_dataset
|
| 195 |
+
from trl import RewardTrainer
|
| 196 |
+
from peft import AutoPeftModelForCausalLM
|
| 197 |
+
|
| 198 |
+
model = AutoPeftModelForCausalLM.from_pretrained("trl-lib/Qwen3-4B-Reward-LoRA", is_trainable=True)
|
| 199 |
+
dataset = load_dataset("trl-lib/Capybara", split="train")
|
| 200 |
+
|
| 201 |
+
trainer = RewardTrainer(
|
| 202 |
+
model=model,
|
| 203 |
+
train_dataset=dataset,
|
| 204 |
+
)
|
| 205 |
+
|
| 206 |
+
trainer.train()
|
| 207 |
+
```
|
| 208 |
+
|
| 209 |
+
> [!TIP]
|
| 210 |
+
> When training adapters, you typically use a higher learning rate (≈1e‑3) since only new parameters are being learned.
|
| 211 |
+
>
|
| 212 |
+
> ```python
|
| 213 |
+
> RewardConfig(learning_rate=1e-3, ...)
|
| 214 |
+
> ```
|
| 215 |
+
|
| 216 |
+
## Tool Calling with Reward Modeling
|
| 217 |
+
|
| 218 |
+
The [`RewardTrainer`] fully supports fine-tuning models with _tool calling_ capabilities. In this case, each dataset example should include:
|
| 219 |
+
|
| 220 |
+
* The conversation messages, including any tool calls (`tool_calls`) and tool responses (`tool` role messages)
|
| 221 |
+
* The list of available tools in the `tools` column, typically provided as JSON schemas
|
| 222 |
+
|
| 223 |
+
For details on the expected dataset structure, see the [Dataset Format — Tool Calling](dataset_formats#tool-calling) section.
|
| 224 |
+
|
| 225 |
+
## RewardTrainer
|
| 226 |
+
|
| 227 |
+
[[autodoc]] RewardTrainer
|
| 228 |
+
- train
|
| 229 |
+
- save_model
|
| 230 |
+
- push_to_hub
|
| 231 |
+
|
| 232 |
+
## RewardConfig
|
| 233 |
+
|
| 234 |
+
[[autodoc]] RewardConfig
|
tasks/tasksmith-1c108f674e97/tests/source/docs/source/rewards.md
ADDED
|
@@ -0,0 +1,19 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Reward Functions
|
| 2 |
+
|
| 3 |
+
This module contains some useful reward functions, primarily intended for use with the [`GRPOTrainer`] and [`RLOOTrainer`].
|
| 4 |
+
|
| 5 |
+
## accuracy_reward
|
| 6 |
+
|
| 7 |
+
[[autodoc]] rewards.accuracy_reward
|
| 8 |
+
|
| 9 |
+
## reasoning_accuracy_reward
|
| 10 |
+
|
| 11 |
+
[[autodoc]] rewards.reasoning_accuracy_reward
|
| 12 |
+
|
| 13 |
+
## think_format_reward
|
| 14 |
+
|
| 15 |
+
[[autodoc]] rewards.think_format_reward
|
| 16 |
+
|
| 17 |
+
## get_soft_overlong_punishment
|
| 18 |
+
|
| 19 |
+
[[autodoc]] rewards.get_soft_overlong_punishment
|
tasks/tasksmith-1c108f674e97/tests/source/docs/source/rloo_trainer.md
ADDED
|
@@ -0,0 +1,642 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# RLOO Trainer
|
| 2 |
+
|
| 3 |
+
[](https://huggingface.co/models?other=rloo,trl)
|
| 4 |
+
|
| 5 |
+
## Overview
|
| 6 |
+
|
| 7 |
+
TRL supports the RLOO Trainer for training language models, as described in the paper [Back to Basics: Revisiting REINFORCE Style
|
| 8 |
+
Optimization for Learning from Human Feedback in LLMs](https://huggingface.co/papers/2402.14740) by [Arash Ahmadian](https://huggingface.co/ArashAhmadian), Chris Cremer, [Matthias Gallé](https://huggingface.co/mgalle), [Marzieh Fadaee](https://huggingface.co/MarziehFadaee), [Julia Kreutzer](https://huggingface.co/JuliaKreutzerCohere), [Ahmet Üstün](https://huggingface.co/ahmetu) and [Sara Hooker](https://huggingface.co/sarahooker).
|
| 9 |
+
|
| 10 |
+
The abstract from the paper is the following:
|
| 11 |
+
|
| 12 |
+
> AI alignment in the shape of Reinforcement Learning from Human Feedback (RLHF) is increasingly treated as a crucial ingredient for high performance large language models. Proximal Policy Optimization (PPO) has been positioned by recent literature as the canonical method for the RL part of RLHF However, it involves both high computational cost and sensitive hyperparameter tuning. We posit that most of the motivational principles that led to the development of PPO are less of a practical concern in RLHF and advocate for a less computationally expensive method that preserves and even increases performance. We revisit the formulation of alignment from human preferences in the context of RL. Keeping simplicity as a guiding principle, we show that many components of PPO are unnecessary in an RLHF context and that far simpler REINFORCE-style optimization variants outperform both PPO and newly proposed “RL-free” methods such as DPO and RAFT. Our work suggests that careful adaptation to LLMs alignment characteristics enables benefiting from online RL optimization at low cost.
|
| 13 |
+
|
| 14 |
+
This post-training method was contributed by [Costa Huang](https://github.com/vwxyzjn) and later refactored by [Shirin Yamani](https://huggingface.co/ShirinYamani).
|
| 15 |
+
|
| 16 |
+
## Quick start
|
| 17 |
+
|
| 18 |
+
This example demonstrates how to train a model using the RLOO method. We train a [Qwen 0.5B Instruct model](https://huggingface.co/Qwen/Qwen2-0.5B-Instruct) with the prompts from the [DeepMath-103K dataset](https://huggingface.co/datasets/trl-lib/DeepMath-103K). You can view the data in the dataset here:
|
| 19 |
+
|
| 20 |
+
<iframe
|
| 21 |
+
src="https://huggingface.co/datasets/trl-lib/DeepMath-103K/embed/viewer/default/train?row=0"
|
| 22 |
+
frameborder="0"
|
| 23 |
+
width="100%"
|
| 24 |
+
height="560px"
|
| 25 |
+
></iframe>
|
| 26 |
+
|
| 27 |
+
Below is the script to train the model.
|
| 28 |
+
|
| 29 |
+
```python
|
| 30 |
+
# train_rloo.py
|
| 31 |
+
from datasets import load_dataset
|
| 32 |
+
from trl import RLOOTrainer
|
| 33 |
+
from trl.rewards import accuracy_reward
|
| 34 |
+
|
| 35 |
+
dataset = load_dataset("trl-lib/DeepMath-103K", split="train")
|
| 36 |
+
|
| 37 |
+
trainer = RLOOTrainer(
|
| 38 |
+
model="Qwen/Qwen2-0.5B-Instruct",
|
| 39 |
+
reward_funcs=accuracy_reward,
|
| 40 |
+
train_dataset=dataset,
|
| 41 |
+
)
|
| 42 |
+
trainer.train()
|
| 43 |
+
```
|
| 44 |
+
|
| 45 |
+
Execute the script using the following command:
|
| 46 |
+
|
| 47 |
+
```bash
|
| 48 |
+
accelerate launch train_rloo.py
|
| 49 |
+
```
|
| 50 |
+
|
| 51 |
+
## Looking deeper into the RLOO method
|
| 52 |
+
|
| 53 |
+
RLOO is an online learning algorithm, meaning it improves iteratively by using the data generated by the trained model itself during training. The intuition behind RLOO objective is to maximize the advantage of the generated completions, while ensuring that the model remains close to the reference policy. To understand how RLOO works, it can be broken down into four main steps: **Generating completions**, **computing the advantage**, **estimating the KL divergence**, and **computing the loss**.
|
| 54 |
+
|
| 55 |
+

|
| 56 |
+
|
| 57 |
+
### Generating completions
|
| 58 |
+
|
| 59 |
+
At each training step, we sample a batch of prompts and generate a set of \\( G \\) completions for each prompt (denoted as \\( o_i \\)).
|
| 60 |
+
|
| 61 |
+
### Computing the reward
|
| 62 |
+
|
| 63 |
+
In RLOO, the reward consists of two components: the reward provided by the reward model (or reward function) and a KL penalty that discourages the policy from deviating too far from a fixed reference policy
|
| 64 |
+
|
| 65 |
+
1. For each of the \\( G \\) generated sequences \\( o_i = (o_{i,1}, \dots, o_{i,T}) \\) conditioned on a query \\( q \\), we compute a scalar reward using a reward model \\( R(o_i, q) \\).
|
| 66 |
+
2. Concurrently, we estimate the KL divergence between the current policy \\( \pi_\theta \\) and the fixed reference policy \\( \pi_{\text{ref}} \\) over the sequence. The KL estimate for sequence \\( o_i \\) is:
|
| 67 |
+
|
| 68 |
+
$$
|
| 69 |
+
\mathbb{D}_{\mathrm{KL}}\!\left[\pi_\theta\|\pi_{\mathrm{ref}}\right] = \sum_{t=1}^T \log \frac{\pi_\theta(o_{i,t} \mid q, o_{i,<t})}{\pi_{\mathrm{ref}}(o_{i,t} \mid q, o_{i,<t})}.
|
| 70 |
+
$$
|
| 71 |
+
|
| 72 |
+
The final reward assigned to sequence \\( o_i \\) is then:
|
| 73 |
+
|
| 74 |
+
$$
|
| 75 |
+
r_i = R(o_i, q) - \beta \, \mathbb{D}_{\mathrm{KL}}\!\left[\pi_\theta \|\pi_{\mathrm{ref}}\right],
|
| 76 |
+
$$
|
| 77 |
+
|
| 78 |
+
where \\( \beta > 0 \\) controls the strength of the KL penalty.
|
| 79 |
+
|
| 80 |
+
> [!TIP]
|
| 81 |
+
> In a purely online setting (`num_iterations = 1`, default), the data are generated by the current policy. In this case, the KL penalty is computed directly using the current policy.
|
| 82 |
+
>
|
| 83 |
+
> In the more general setting (e.g., multiple gradient steps per batch), the data are instead generated by an earlier snapshot \\( \pi_{\text{old}} \\). To keep the penalty consistent with the sampling distribution, the KL is defined with respect to this policy:
|
| 84 |
+
>
|
| 85 |
+
> $$
|
| 86 |
+
> \mathbb{D}_{\mathrm{KL}}\!\left[\pi_{\text{old}} \,\|\, \pi_{\text{ref}}\right].
|
| 87 |
+
> $$
|
| 88 |
+
>
|
| 89 |
+
> Equivalently, for a sampled sequence $o$, the Monte Carlo estimate is
|
| 90 |
+
>
|
| 91 |
+
> $$
|
| 92 |
+
> \mathbb{D}_{\mathrm{KL}}\!\left[\pi_{\text{old}} \|\pi_{\mathrm{ref}}\right] = \sum_{t=1}^T \log \frac{\pi_{\text{old}}(o_{i,t} \mid q, o_{i,<t})}{\pi_{\mathrm{ref}}(o_{i,t} \mid q, o_{i,<t})}.
|
| 93 |
+
> $$
|
| 94 |
+
|
| 95 |
+
### Computing the advantage
|
| 96 |
+
|
| 97 |
+
Once the rewards for each completion have been computed, we calculate a baseline as the average reward of all other samples in the same batch, excluding the current sample. This baseline is used to reduce the variance of the policy gradient estimate. The advantage for each completion is then obtained as the difference between its own reward and this leave-one-out baseline.
|
| 98 |
+
|
| 99 |
+
Formally, for a batch of G completions, the baseline for completion is:
|
| 100 |
+
$$
|
| 101 |
+
b_i = \frac{1}{G-1} \sum_{j \neq i} r_j
|
| 102 |
+
$$
|
| 103 |
+
|
| 104 |
+
and then the advantage for each completion is computed as the difference between its reward and the baseline:
|
| 105 |
+
|
| 106 |
+
$$
|
| 107 |
+
A_i = r_i - b_i
|
| 108 |
+
$$
|
| 109 |
+
|
| 110 |
+
### Computing the loss
|
| 111 |
+
|
| 112 |
+
The REINFORCE loss is simply defined as:
|
| 113 |
+
|
| 114 |
+
$$
|
| 115 |
+
\mathcal{L}_{\text{RLOO}}(\theta) = - \frac{1}{G} \sum_{i=1}^G \hat{A}_i \, \log \pi_\theta(o_i \mid q)
|
| 116 |
+
$$
|
| 117 |
+
|
| 118 |
+
In practice, performing multiple gradient steps on the same batch makes the actions effectively off-policy relative to the current parameters. To correct for this, we introduce the importance sampling ratio. To prevent excessively large updates when the policy changes between sampling and gradient steps, we clip this ratio:
|
| 119 |
+
|
| 120 |
+
$$
|
| 121 |
+
\mathcal{L}_{\text{RLOO}}(\theta) = - \frac{1}{G} \sum_{i=1}^G \min \left( \frac{\pi_\theta(o_i \mid q)}{\pi_{\theta_\text{old}}(o_i \mid q)} \hat{A}_i, \, \text{clip}\left(\frac{\pi_\theta(o_i \mid q)}{\pi_{\theta_\text{old}}(o_i \mid q)}, 1-\epsilon, 1+\epsilon\right) \hat{A}_i \right)
|
| 122 |
+
$$
|
| 123 |
+
|
| 124 |
+
In a fully online, single-step setting (default), \\( \frac{\pi_\theta(o_i \mid q)}{\pi_{\theta_\text{old}}(o_i \mid q)} = 1 \\) and this reduces to standard REINFORCE.
|
| 125 |
+
|
| 126 |
+
## Logged metrics
|
| 127 |
+
|
| 128 |
+
While training and evaluating, we record the following reward metrics:
|
| 129 |
+
|
| 130 |
+
- `num_tokens`: The total number of tokens processed so far, including both prompts and completions.
|
| 131 |
+
- `step_time`: The average time (in seconds) taken per training step (including generation).
|
| 132 |
+
- `completions/mean_length`: The average length of generated completions.
|
| 133 |
+
- `completions/min_length`: The minimum length of generated completions.
|
| 134 |
+
- `completions/max_length`: The maximum length of generated completions.
|
| 135 |
+
- `completions/mean_terminated_length`: The average length of generated completions that terminate with EOS.
|
| 136 |
+
- `completions/min_terminated_length`: The minimum length of generated completions that terminate with EOS.
|
| 137 |
+
- `completions/max_terminated_length`: The maximum length of generated completions that terminate with EOS.
|
| 138 |
+
- `completions/clipped_ratio`: The ratio of truncated (clipped) completions.
|
| 139 |
+
- `reward/{reward_func_name}/mean`: The average reward from a specific reward function.
|
| 140 |
+
- `reward/{reward_func_name}/std`: The standard deviation of the reward from a specific reward function.
|
| 141 |
+
- `reward`: The overall average reward after summing rewards across functions (weighted by `reward_weights`).
|
| 142 |
+
- `reward_std`: The standard deviation of summed rewards across functions (weighted by `reward_weights`), computed over the full batch.
|
| 143 |
+
- `frac_reward_zero_std`: The fraction of samples in the generation batch with a reward std of zero, implying there is little diversity for that prompt (all answers are correct or incorrect).
|
| 144 |
+
- `entropy`: Average entropy of token predictions across generated completions. (If `mask_truncated_completions=True`, masked sequences tokens are excluded.)
|
| 145 |
+
- `kl`: The average KL divergence between the model and the reference model, calculated over generated completions. Logged only if `beta` is nonzero.
|
| 146 |
+
- `clip_ratio/region_mean`: The ratio of sequence probabilities where the RLOO objective is clipped to stay within the trust region: \\( \text{clip}\left( r_{i}(\theta), 1 - \epsilon_\mathrm{low}, 1 + \epsilon_\mathrm{high} \right)\,, \quad r_{i}(\theta) = \frac{\pi_\theta(o_{i} \mid q)}{\pi_{\theta_{\text{old}}}(o_{i} \mid q)} \\). A higher value means more samples are clipped, which constrains how much the policy $\pi_\theta$ can change.
|
| 147 |
+
- `clip_ratio/low_mean`: The average ratio of sequence probabilities that were clipped on the lower bound of the trust region: \\(r_{i,t}(\theta) < 1 - \epsilon_\mathrm{low}\\).
|
| 148 |
+
- `clip_ratio/low_min`: The minimum ratio of sequence probabilities that were clipped on the lower bound of the trust region: \\(r_{i,t}(\theta) < 1 - \epsilon_\mathrm{low}\\).
|
| 149 |
+
- `clip_ratio/high_mean`: The average ratio of sequence probabilities that were clipped on the upper bound of the trust region: \\(r_{i,t}(\theta) > 1 + \epsilon_\mathrm{high}\\).
|
| 150 |
+
- `clip_ratio/high_max`: The maximum ratio of sequence probabilities that were clipped on the upper bound of the trust region: \\(r_{i,t}(\theta) > 1 + \epsilon_\mathrm{high}\\).
|
| 151 |
+
|
| 152 |
+
## Customization
|
| 153 |
+
|
| 154 |
+
### Speed up training with vLLM-powered generation
|
| 155 |
+
|
| 156 |
+
Generation is often the main bottleneck when training with online methods. To accelerate generation, you can use [vLLM](https://github.com/vllm-project/vllm), a high-throughput, low-latency inference engine for LLMs. To enable it, first install the package with
|
| 157 |
+
|
| 158 |
+
```shell
|
| 159 |
+
pip install trl[vllm]
|
| 160 |
+
```
|
| 161 |
+
|
| 162 |
+
We support two ways of using vLLM during training: **server mode** and **colocate mode**.
|
| 163 |
+
|
| 164 |
+
#### Option 1: Colocate mode
|
| 165 |
+
|
| 166 |
+
In this mode, vLLM runs inside the trainer process and shares GPU memory with the training model. This avoids launching a separate server and can improve GPU utilization, but may lead to memory contention on the training GPUs. This is the default mode.
|
| 167 |
+
|
| 168 |
+
```python
|
| 169 |
+
from trl import RLOOConfig
|
| 170 |
+
|
| 171 |
+
training_args = RLOOConfig(
|
| 172 |
+
...,
|
| 173 |
+
use_vllm=True, # vllm_mode="colocate" by default
|
| 174 |
+
)
|
| 175 |
+
```
|
| 176 |
+
|
| 177 |
+
#### Option 2: Server mode
|
| 178 |
+
|
| 179 |
+
In this mode, vLLM runs in a separate process (and using separate GPUs) and communicates with the trainer via HTTP. This is ideal if you have dedicated GPUs for inference.
|
| 180 |
+
|
| 181 |
+
1. **Start the vLLM server**:
|
| 182 |
+
|
| 183 |
+
```bash
|
| 184 |
+
trl vllm-serve --model <model_name>
|
| 185 |
+
```
|
| 186 |
+
|
| 187 |
+
2. **Enable server mode in your training script**:
|
| 188 |
+
|
| 189 |
+
```python
|
| 190 |
+
from trl import RLOOConfig
|
| 191 |
+
|
| 192 |
+
training_args = RLOOConfig(
|
| 193 |
+
...,
|
| 194 |
+
use_vllm=True,
|
| 195 |
+
vllm_mode="server",
|
| 196 |
+
)
|
| 197 |
+
```
|
| 198 |
+
|
| 199 |
+
> [!WARNING]
|
| 200 |
+
> Make sure that the server is using different GPUs than the trainer, otherwise you may run into NCCL errors. You can specify the GPUs to use with the `CUDA_VISIBLE_DEVICES` environment variable.
|
| 201 |
+
|
| 202 |
+
> [!TIP]
|
| 203 |
+
> Depending on the model size and the overall GPU memory requirements for training, you may need to adjust the `vllm_gpu_memory_utilization` parameter in [`RLOOConfig`] to avoid underutilization or out-of-memory errors.
|
| 204 |
+
>
|
| 205 |
+
> We provide a [HF Space](https://huggingface.co/spaces/trl-lib/recommend-vllm-memory) to help estimate the recommended GPU memory utilization based on your model configuration and experiment settings. Simply use it as follows to get `vllm_gpu_memory_utilization` recommendation:
|
| 206 |
+
>
|
| 207 |
+
> <iframe src="https://trl-lib-recommend-vllm-memory.hf.space" frameborder="0" width="850" height="450"></iframe>
|
| 208 |
+
>
|
| 209 |
+
> If the recommended value does not work in your environment, we suggest adding a small buffer (e.g., +0.05 or +0.1) to the recommended value to ensure stability.
|
| 210 |
+
>
|
| 211 |
+
> If you still find you are getting out-of-memory errors set `vllm_enable_sleep_mode` to True and the vllm parameters and cache will be offloaded during the optimization step. For more information, see [Reducing Memory Usage with vLLM Sleep Mode](reducing_memory_usage#vllm-sleep-mode).
|
| 212 |
+
|
| 213 |
+
> [!TIP]
|
| 214 |
+
> By default, RLOO uses `MASTER_ADDR=localhost` and `MASTER_PORT=12345` for vLLM, but you can override these values by setting the environment variables accordingly.
|
| 215 |
+
|
| 216 |
+
For more information, see [Speeding up training with vLLM](speeding_up_training#vllm-for-fast-generation-in-online-methods).
|
| 217 |
+
|
| 218 |
+
### RLOO at scale: train a 70B+ Model on multiple nodes
|
| 219 |
+
|
| 220 |
+
When training large models like **Qwen2.5-72B**, you need several key optimizations to make the training efficient and scalable across multiple GPUs and nodes. These include:
|
| 221 |
+
|
| 222 |
+
- **DeepSpeed ZeRO Stage 3**: ZeRO leverages data parallelism to distribute model states (weights, gradients, optimizer states) across multiple GPUs and CPUs, reducing memory and compute requirements on each device. Since large models cannot fit on a single GPU, using ZeRO Stage 3 is required for training such models. For more details, see [DeepSpeed Integration](deepspeed_integration).
|
| 223 |
+
- **Accelerate**: Accelerate is a library that simplifies distributed training across multiple GPUs and nodes. It provides a simple API to launch distributed training and handles the complexities of distributed training, such as data parallelism, gradient accumulation, and distributed data loading. For more details, see [Distributing Training](distributing_training).
|
| 224 |
+
- **vLLM**: See the previous section on how to use vLLM to speed up generation.
|
| 225 |
+
|
| 226 |
+
Below is an example SLURM script to train a 70B model with RLOO on multiple nodes. This script trains a model on 4 nodes and uses the 5th node for vLLM-powered generation.
|
| 227 |
+
|
| 228 |
+
```sh
|
| 229 |
+
#!/bin/bash
|
| 230 |
+
#SBATCH --nodes=5
|
| 231 |
+
#SBATCH --gres=gpu:8
|
| 232 |
+
|
| 233 |
+
# Get the list of allocated nodes
|
| 234 |
+
NODELIST=($(scontrol show hostnames $SLURM_JOB_NODELIST))
|
| 235 |
+
|
| 236 |
+
# Assign the first 4 nodes for training and the 5th node for vLLM
|
| 237 |
+
TRAIN_NODES="${NODELIST[@]:0:4}" # Nodes 0, 1, 2, 3 for training
|
| 238 |
+
VLLM_NODE="${NODELIST[4]}" # Node 4 for vLLM
|
| 239 |
+
|
| 240 |
+
# Run training on the first 4 nodes (Group 1)
|
| 241 |
+
srun --nodes=4 --ntasks=4 --nodelist="${NODELIST[@]:0:4}" accelerate launch \
|
| 242 |
+
--config_file examples/accelerate_configs/deepspeed_zero3.yaml \
|
| 243 |
+
--num_processes 32 \
|
| 244 |
+
--num_machines 4 \
|
| 245 |
+
--main_process_ip ${NODELIST[0]} \
|
| 246 |
+
--machine_rank $SLURM_PROCID \
|
| 247 |
+
--rdzv_backend c10d \
|
| 248 |
+
train_rloo.py \
|
| 249 |
+
--server_ip $VLLM_NODE &
|
| 250 |
+
|
| 251 |
+
# Run vLLM server on the 5th node (Group 2)
|
| 252 |
+
srun --nodes=1 --ntasks=1 --nodelist="${NODELIST[4]}" trl vllm-serve --model Qwen/Qwen2.5-72B --tensor_parallel_size 8 &
|
| 253 |
+
|
| 254 |
+
wait
|
| 255 |
+
```
|
| 256 |
+
|
| 257 |
+
```python
|
| 258 |
+
import argparse
|
| 259 |
+
|
| 260 |
+
from datasets import load_dataset
|
| 261 |
+
from trl import RLOOTrainer, RLOOConfig
|
| 262 |
+
|
| 263 |
+
def main():
|
| 264 |
+
parser = argparse.ArgumentParser()
|
| 265 |
+
parser.add_argument("--vllm_server_host", type=str, default="", help="The server IP")
|
| 266 |
+
args = parser.parse_args()
|
| 267 |
+
|
| 268 |
+
# Example dataset from TLDR
|
| 269 |
+
dataset = load_dataset("trl-lib/tldr", split="train")
|
| 270 |
+
|
| 271 |
+
# Dummy reward function: count the number of unique characters in the completions
|
| 272 |
+
def reward_num_unique_chars(completions, **kwargs):
|
| 273 |
+
return [len(set(c)) for c in completions]
|
| 274 |
+
|
| 275 |
+
training_args = RLOOConfig(
|
| 276 |
+
output_dir="Qwen2.5-72B-RLOO",
|
| 277 |
+
per_device_train_batch_size=4,
|
| 278 |
+
bf16=True,
|
| 279 |
+
use_vllm=True,
|
| 280 |
+
vllm_mode="server",
|
| 281 |
+
vllm_server_host=args.vllm_server_host.replace("ip-", "").replace("-", "."), # from ip-X-X-X-X to X.X.X.X
|
| 282 |
+
)
|
| 283 |
+
|
| 284 |
+
trainer = RLOOTrainer(model="Qwen/Qwen2.5-72B", args=training_args, reward_funcs=reward_num_unique_chars, train_dataset=dataset)
|
| 285 |
+
trainer.train()
|
| 286 |
+
|
| 287 |
+
if __name__=="__main__":
|
| 288 |
+
main()
|
| 289 |
+
```
|
| 290 |
+
|
| 291 |
+
### Using a custom reward function
|
| 292 |
+
|
| 293 |
+
The [`RLOOTrainer`] supports using custom reward functions instead of dense reward models. To ensure compatibility, your reward function must satisfy the following requirements:
|
| 294 |
+
|
| 295 |
+
Reward functions can be either synchronous Python callables or asynchronous `async def` coroutines. When you provide multiple asynchronous reward functions, they are awaited concurrently (run in parallel via `asyncio.gather`) so their latency overlaps.
|
| 296 |
+
|
| 297 |
+
1. **Input arguments**:
|
| 298 |
+
- The function must accept the following as keyword arguments:
|
| 299 |
+
- `prompts` (contains the prompts),
|
| 300 |
+
- `completions` (contains the generated completions),
|
| 301 |
+
- `completion_ids` (contains the tokenized completions),
|
| 302 |
+
- `trainer_state` ([`~transformers.TrainerState`]): The current state of the trainer. This can be used to implement dynamic reward functions, such as curriculum learning, where the reward is adjusted based on the training progress.
|
| 303 |
+
- `log_extra`: a callable `log_extra(column: str, values: list)` to add extra columns to the completions table. See Example 6. In distributed training, it's important that all processes log the same set of keys.
|
| 304 |
+
- `log_metric`: a callable `log_metric(name: str, value: float)` to log scalar metrics as plots alongside `kl`, `entropy`, etc. See Example 6. In distributed training, it's important that all processes log the same set of keys.
|
| 305 |
+
- All column names (but `prompt`) that the dataset may have. For example, if the dataset contains a column named `ground_truth`, the function will be called with `ground_truth` as a keyword argument.
|
| 306 |
+
|
| 307 |
+
The easiest way to comply with this requirement is to use `**kwargs` in the function signature.
|
| 308 |
+
- Depending on the dataset format, the input will vary:
|
| 309 |
+
- For [standard format](dataset_formats#standard), `prompts` and `completions` will be lists of strings.
|
| 310 |
+
- For [conversational format](dataset_formats#conversational), `prompts` and `completions` will be lists of message dictionaries.
|
| 311 |
+
|
| 312 |
+
2. **Return value**: The function must return a list of floats. Each float represents the reward corresponding to a single completion.
|
| 313 |
+
|
| 314 |
+
#### Example 1: Reward longer completions
|
| 315 |
+
|
| 316 |
+
Below is an example of a reward function for a standard format that rewards longer completions:
|
| 317 |
+
|
| 318 |
+
```python
|
| 319 |
+
def reward_func(completion_ids, **kwargs):
|
| 320 |
+
"""Reward function that assigns higher scores to longer completions (in terms of token count)."""
|
| 321 |
+
return [float(len(ids)) for ids in completion_ids]
|
| 322 |
+
```
|
| 323 |
+
|
| 324 |
+
You can test it as follows:
|
| 325 |
+
|
| 326 |
+
```python
|
| 327 |
+
>>> prompts = ["The sky is", "The sun is"] # not used in the reward function, but the trainer will pass it
|
| 328 |
+
>>> completions = [" blue.", " in the sky."] # not used in the reward function, but the trainer will pass it
|
| 329 |
+
>>> completion_ids = [[6303, 13], [304, 279, 12884, 13]]
|
| 330 |
+
>>> reward_func(prompts=prompts, completions=completions, completion_ids=completion_ids)
|
| 331 |
+
[2.0, 4.0]
|
| 332 |
+
```
|
| 333 |
+
|
| 334 |
+
#### Example 1.1: Reward longer completions (based on the number of characters)
|
| 335 |
+
|
| 336 |
+
Same as the previous example, but this time the reward function is based on the number of characters instead of tokens.
|
| 337 |
+
|
| 338 |
+
```python
|
| 339 |
+
def reward_func(completions, **kwargs):
|
| 340 |
+
"""Reward function that assigns higher scores to longer completions (in terms of character count)."""
|
| 341 |
+
return [float(len(completion)) for completion in completions]
|
| 342 |
+
```
|
| 343 |
+
|
| 344 |
+
You can test it as follows:
|
| 345 |
+
|
| 346 |
+
```python
|
| 347 |
+
>>> prompts = ["The sky is", "The sun is"]
|
| 348 |
+
>>> completions = [" blue.", " in the sky."]
|
| 349 |
+
>>> completion_ids = [[6303, 13], [304, 279, 12884, 13]] # not used in the reward function, but the trainer will pass it
|
| 350 |
+
>>> reward_func(prompts=prompts, completions=completions, completion_ids=completion_ids)
|
| 351 |
+
[6.0, 12.0]
|
| 352 |
+
```
|
| 353 |
+
|
| 354 |
+
#### Example 2: Reward completions with a specific format
|
| 355 |
+
|
| 356 |
+
Below is an example of a reward function that checks if the completion has a specific format. This example is inspired by the _format reward_ function used in the paper [DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning](https://huggingface.co/papers/2501.12948).
|
| 357 |
+
It is designed for a conversational format, where prompts and completions consist of structured messages.
|
| 358 |
+
|
| 359 |
+
```python
|
| 360 |
+
import re
|
| 361 |
+
|
| 362 |
+
def format_reward_func(completions, **kwargs):
|
| 363 |
+
"""Reward function that checks if the completion has a specific format."""
|
| 364 |
+
pattern = r"^<think>.*?</think><answer>.*?</answer>$"
|
| 365 |
+
completion_contents = [completion[0]["content"] for completion in completions]
|
| 366 |
+
matches = [re.match(pattern, content) for content in completion_contents]
|
| 367 |
+
return [1.0 if match else 0.0 for match in matches]
|
| 368 |
+
```
|
| 369 |
+
|
| 370 |
+
You can test this function as follows:
|
| 371 |
+
|
| 372 |
+
```python
|
| 373 |
+
>>> prompts = [
|
| 374 |
+
... [{"role": "assistant", "content": "What is the result of (1 + 2) * 4?"}],
|
| 375 |
+
... [{"role": "assistant", "content": "What is the result of (3 + 1) * 2?"}],
|
| 376 |
+
... ]
|
| 377 |
+
>>> completions = [
|
| 378 |
+
... [{"role": "assistant", "content": "<think>The sum of 1 and 2 is 3, which we multiply by 4 to get 12.</think><answer>(1 + 2) * 4 = 12</answer>"}],
|
| 379 |
+
... [{"role": "assistant", "content": "The sum of 3 and 1 is 4, which we multiply by 2 to get 8. So (3 + 1) * 2 = 8."}],
|
| 380 |
+
... ]
|
| 381 |
+
>>> format_reward_func(prompts=prompts, completions=completions)
|
| 382 |
+
[1.0, 0.0]
|
| 383 |
+
```
|
| 384 |
+
|
| 385 |
+
#### Example 3: Reward completions based on a reference
|
| 386 |
+
|
| 387 |
+
Below is an example of a reward function that checks if the completion is correct. This example is inspired by the _accuracy reward_ function used in the paper [DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning](https://huggingface.co/papers/2501.12948).
|
| 388 |
+
This example is designed for [standard format](dataset_formats#standard), where the dataset contains a column named `ground_truth`.
|
| 389 |
+
|
| 390 |
+
```python
|
| 391 |
+
import re
|
| 392 |
+
|
| 393 |
+
def reward_func(completions, ground_truth, **kwargs):
|
| 394 |
+
# Regular expression to capture content inside \boxed{}
|
| 395 |
+
matches = [re.search(r"\\boxed\{(.*?)\}", completion) for completion in completions]
|
| 396 |
+
contents = [match.group(1) if match else "" for match in matches]
|
| 397 |
+
# Reward 1 if the content is the same as the ground truth, 0 otherwise
|
| 398 |
+
return [1.0 if c == gt else 0.0 for c, gt in zip(contents, ground_truth)]
|
| 399 |
+
```
|
| 400 |
+
|
| 401 |
+
You can test this function as follows:
|
| 402 |
+
|
| 403 |
+
```python
|
| 404 |
+
>>> prompts = ["Problem: Solve the equation $2x + 3 = 7$. Solution:", "Problem: Solve the equation $3x - 5 = 10$."]
|
| 405 |
+
>>> completions = [r" The solution is \boxed{2}.", r" The solution is \boxed{6}."]
|
| 406 |
+
>>> ground_truth = ["2", "5"]
|
| 407 |
+
>>> reward_func(prompts=prompts, completions=completions, ground_truth=ground_truth)
|
| 408 |
+
[1.0, 0.0]
|
| 409 |
+
```
|
| 410 |
+
|
| 411 |
+
#### Example 4: Multi-task reward functions
|
| 412 |
+
|
| 413 |
+
Below is an example of using multiple reward functions in the [`RLOOTrainer`]. In this example, we define two task-specific reward functions: `math_reward_func` and `coding_reward_func`. The `math_reward_func` rewards math problems based on their correctness, while the `coding_reward_func` rewards coding problems based on whether the solution works.
|
| 414 |
+
|
| 415 |
+
```python
|
| 416 |
+
from datasets import Dataset
|
| 417 |
+
from trl import RLOOTrainer
|
| 418 |
+
|
| 419 |
+
# Define a dataset that contains both math and coding problems
|
| 420 |
+
dataset = Dataset.from_list(
|
| 421 |
+
[
|
| 422 |
+
{"prompt": "What is 2+2?", "task": "math"},
|
| 423 |
+
{"prompt": "Write a function that returns the sum of two numbers.", "task": "code"},
|
| 424 |
+
{"prompt": "What is 3*4?", "task": "math"},
|
| 425 |
+
{"prompt": "Write a function that returns the product of two numbers.", "task": "code"},
|
| 426 |
+
]
|
| 427 |
+
)
|
| 428 |
+
|
| 429 |
+
# Math-specific reward function
|
| 430 |
+
def math_reward_func(prompts, completions, task, **kwargs):
|
| 431 |
+
rewards = []
|
| 432 |
+
for prompt, completion, t in zip(prompts, completions, task):
|
| 433 |
+
if t == "math":
|
| 434 |
+
# Calculate math-specific reward
|
| 435 |
+
correct = check_math_solution(prompt, completion)
|
| 436 |
+
reward = 1.0 if correct else -1.0
|
| 437 |
+
rewards.append(reward)
|
| 438 |
+
else:
|
| 439 |
+
# Return None for non-math tasks
|
| 440 |
+
rewards.append(None)
|
| 441 |
+
return rewards
|
| 442 |
+
|
| 443 |
+
# Coding-specific reward function
|
| 444 |
+
def coding_reward_func(prompts, completions, task, **kwargs):
|
| 445 |
+
rewards = []
|
| 446 |
+
for prompt, completion, t in zip(prompts, completions, task):
|
| 447 |
+
if t == "coding":
|
| 448 |
+
# Calculate coding-specific reward
|
| 449 |
+
works = test_code_solution(prompt, completion)
|
| 450 |
+
reward = 1.0 if works else -1.0
|
| 451 |
+
rewards.append(reward)
|
| 452 |
+
else:
|
| 453 |
+
# Return None for non-coding tasks
|
| 454 |
+
rewards.append(None)
|
| 455 |
+
return rewards
|
| 456 |
+
|
| 457 |
+
# Use both task-specific reward functions
|
| 458 |
+
trainer = RLOOTrainer(
|
| 459 |
+
model="Qwen/Qwen2-0.5B-Instruct",
|
| 460 |
+
reward_funcs=[math_reward_func, coding_reward_func],
|
| 461 |
+
train_dataset=dataset,
|
| 462 |
+
)
|
| 463 |
+
|
| 464 |
+
trainer.train()
|
| 465 |
+
```
|
| 466 |
+
|
| 467 |
+
In this example, the `math_reward_func` and `coding_reward_func` are designed to work with a mixed dataset that contains both math and coding problems. The `task` column in the dataset is used to determine which reward function to apply to each problem. If there is no relevant reward function for a sample in the dataset, the reward function will return `None`, and the [`RLOOTrainer`] will continue with the valid functions and tasks. This allows the [`RLOOTrainer`] to handle multiple reward functions with different applicability.
|
| 468 |
+
|
| 469 |
+
Note that the [`RLOOTrainer`] will ignore the `None` rewards returned by the reward functions and only consider the rewards returned by the relevant functions. This ensures that the model is trained on the relevant tasks and ignores the tasks for which there is no relevant reward function.
|
| 470 |
+
|
| 471 |
+
#### Example 5: Asynchronous reward functions
|
| 472 |
+
|
| 473 |
+
Custom reward functions can also be defined as `async def` coroutines. This is useful if your reward depends on slow I/O (for example, calling a remote service). When you pass multiple async reward functions, [`RLOOTrainer`] executes them concurrently so their latency overlaps.
|
| 474 |
+
|
| 475 |
+
Below is a minimal example of an async reward function that simulates an I/O-bound operation:
|
| 476 |
+
|
| 477 |
+
```python
|
| 478 |
+
import asyncio
|
| 479 |
+
|
| 480 |
+
async def async_reward_func(prompts, completions, **kwargs):
|
| 481 |
+
# Simulate an I/O-bound call (e.g., HTTP request, database lookup)
|
| 482 |
+
await asyncio.sleep(0.01)
|
| 483 |
+
# Simple toy reward: 1.0 if the completion is non-empty, else 0.0
|
| 484 |
+
return [1.0 if completion else 0.0 for completion in completions]
|
| 485 |
+
```
|
| 486 |
+
|
| 487 |
+
#### Example 6: Logging extra columns and metrics
|
| 488 |
+
|
| 489 |
+
Below is an example of a reward function that logs extra columns to the completions table and scalar metrics as plots.
|
| 490 |
+
|
| 491 |
+
```python
|
| 492 |
+
import re
|
| 493 |
+
|
| 494 |
+
def reward_func(completions, ground_truth, log_extra=None, log_metric=None, **kwargs):
|
| 495 |
+
extracted = [re.search(r"\\boxed\{(.*?)\}", c) for c in completions]
|
| 496 |
+
extracted = [m.group(1) if m else None for m in extracted]
|
| 497 |
+
rewards = [1.0 if e == gt else 0.0 for e, gt in zip(extracted, ground_truth)]
|
| 498 |
+
|
| 499 |
+
if log_extra:
|
| 500 |
+
log_extra("golden_answer", list(ground_truth))
|
| 501 |
+
log_extra("extracted_answer", [e or "[none]" for e in extracted])
|
| 502 |
+
|
| 503 |
+
if log_metric:
|
| 504 |
+
log_metric("accuracy", sum(rewards) / len(rewards))
|
| 505 |
+
|
| 506 |
+
return rewards
|
| 507 |
+
```
|
| 508 |
+
|
| 509 |
+
#### Passing the reward function to the trainer
|
| 510 |
+
|
| 511 |
+
To use your custom reward function, pass it to the [`RLOOTrainer`] as follows:
|
| 512 |
+
|
| 513 |
+
```python
|
| 514 |
+
from trl import RLOOTrainer
|
| 515 |
+
|
| 516 |
+
trainer = RLOOTrainer(
|
| 517 |
+
reward_funcs=reward_func,
|
| 518 |
+
...,
|
| 519 |
+
)
|
| 520 |
+
```
|
| 521 |
+
|
| 522 |
+
You can pass several reward functions as a list; this list may include both synchronous and asynchronous functions:
|
| 523 |
+
|
| 524 |
+
```python
|
| 525 |
+
from trl import RLOOTrainer
|
| 526 |
+
|
| 527 |
+
trainer = RLOOTrainer(
|
| 528 |
+
reward_funcs=[reward_func, async_reward_func1, async_reward_func2],
|
| 529 |
+
...,
|
| 530 |
+
)
|
| 531 |
+
```
|
| 532 |
+
|
| 533 |
+
and the reward will be computed as the sum of the rewards from each function, or the weighted sum if `reward_weights` is provided in the config.
|
| 534 |
+
|
| 535 |
+
Note that [`RLOOTrainer`] supports multiple reward functions of different types. See the parameters documentation for more details.
|
| 536 |
+
|
| 537 |
+
## Vision-Language Model (VLM) Training
|
| 538 |
+
|
| 539 |
+
RLOO supports training Vision-Language Models (VLMs) on multimodal datasets containing both text and images.
|
| 540 |
+
|
| 541 |
+
### Supported Models
|
| 542 |
+
|
| 543 |
+
Tested with:
|
| 544 |
+
|
| 545 |
+
- **Gemma3** — e.g., `google/gemma-3-4b-it`
|
| 546 |
+
- **LLaVA-NeXT** — e.g., `llava-hf/llava-v1.6-mistral-7b-hf`
|
| 547 |
+
- **Qwen2-VL** — e.g., `Qwen/Qwen2-VL-2B-Instruct`
|
| 548 |
+
- **Qwen2.5-VL** — e.g., `Qwen/Qwen2.5-VL-3B-Instruct`
|
| 549 |
+
- **SmolVLM2** — e.g., `HuggingFaceTB/SmolVLM2-2.2B-Instruct`
|
| 550 |
+
|
| 551 |
+
> [!TIP]
|
| 552 |
+
> Compatibility with all VLMs is not guaranteed. If you believe a model should be supported, feel free to open an issue on GitHub — or better yet, submit a pull request with the required changes.
|
| 553 |
+
|
| 554 |
+
### Quick Start
|
| 555 |
+
|
| 556 |
+
Use [rloo\_vlm.py](https://github.com/huggingface/trl/blob/main/examples/scripts/rloo_vlm.py) to fine-tune a VLM. Example command for training on [`lmms-lab/multimodal-open-r1-8k-verified`](https://huggingface.co/datasets/lmms-lab/multimodal-open-r1-8k-verified):
|
| 557 |
+
|
| 558 |
+
```bash
|
| 559 |
+
accelerate launch \
|
| 560 |
+
--config_file=examples/accelerate_configs/deepspeed_zero3.yaml \
|
| 561 |
+
examples/scripts/rloo_vlm.py \
|
| 562 |
+
--model_name_or_path Qwen/Qwen2.5-VL-3B-Instruct \
|
| 563 |
+
--output_dir rloo-Qwen2.5-VL-3B-Instruct \
|
| 564 |
+
--learning_rate 1e-5 \
|
| 565 |
+
--dtype bfloat16 \
|
| 566 |
+
--max_completion_length 1024 \
|
| 567 |
+
--use_vllm \
|
| 568 |
+
--vllm_mode colocate \
|
| 569 |
+
--use_peft \
|
| 570 |
+
--lora_target_modules "q_proj", "v_proj" \
|
| 571 |
+
--log_completions
|
| 572 |
+
```
|
| 573 |
+
|
| 574 |
+
### Configuration Tips
|
| 575 |
+
|
| 576 |
+
- Use LoRA on vision-language projection layers
|
| 577 |
+
- Enable 4-bit quantization to reduce memory usage
|
| 578 |
+
- VLMs are memory-intensive — start with smaller batch sizes
|
| 579 |
+
- Most models are compatible with vLLM (`server` and `colocate` modes)
|
| 580 |
+
|
| 581 |
+
### Dataset Format
|
| 582 |
+
|
| 583 |
+
Each training sample should include:
|
| 584 |
+
|
| 585 |
+
- `prompt`: Text formatted via the processor's chat template
|
| 586 |
+
- `image`/`images`: PIL Image or list of PIL Images
|
| 587 |
+
|
| 588 |
+
The trainer automatically handles image-to-tensor conversion via the model’s image processor.
|
| 589 |
+
|
| 590 |
+
## RLOOTrainer
|
| 591 |
+
|
| 592 |
+
[[autodoc]] RLOOTrainer
|
| 593 |
+
- train
|
| 594 |
+
- save_model
|
| 595 |
+
- push_to_hub
|
| 596 |
+
|
| 597 |
+
## RLOOConfig
|
| 598 |
+
|
| 599 |
+
[[autodoc]] RLOOConfig
|
| 600 |
+
|
| 601 |
+
## References
|
| 602 |
+
|
| 603 |
+
1. [RLOO Paper](https://openreview.net/pdf?id=r1lgTGL5DE)
|
| 604 |
+
2. [Paper Back to Basics: Revisiting REINFORCE Style Optimization for Learning from Human Feedback in LLMs](https://huggingface.co/papers/2402.14740)
|
| 605 |
+
3. [Paper - REINFORCE++: A Simple and Efficient Approach for Aligning Large Language Models](https://huggingface.co/papers/2501.03262)
|
| 606 |
+
4. [Blog Post - Putting RL back in RLHF](https://huggingface.co/blog/putting_rl_back_in_rlhf_with_rloo)
|
| 607 |
+
5. [Blog Post - Unraveling RLHF and Its Variants: Progress and Practical Engineering Insights](https://hijkzzz.notion.site/unraveling-rlhf-and-its-variants-engineering-insights#147d9a33ecc9806090f3d5c749d31f05)
|
| 608 |
+
6. [Youtube - RLOO: A Cost-Efficient Optimization for Learning from Human Feedback in LLMs](https://www.youtube.com/watch?v=86asXGPK6RU&ab_channel=BuzzRobot)
|
| 609 |
+
|
| 610 |
+
## Migration Guide from the old implementation (0.21 and below)
|
| 611 |
+
|
| 612 |
+
With the release of version 0.22.0, we have revamped the [`RLOOTrainer`] to be more aligned with other online trainers in the library, like [`GRPOTrainer`]. This new implementation introduces several changes to the configuration parameters and overall structure of the trainer.
|
| 613 |
+
Below is a summary of the key changes for [`RLOOConfig`]:
|
| 614 |
+
|
| 615 |
+
| TRL ≤ 0.21.x | TRL ≥ 0.22.0 |
|
| 616 |
+
| --- | --- |
|
| 617 |
+
| `rloo_k` | renamed to `num_generations` |
|
| 618 |
+
| `cliprange` | renamed to `epsilon` |
|
| 619 |
+
| `kl_coef` | renamed to `beta` |
|
| 620 |
+
| `exp_name` | renamed to `run_name`. Use `run_name = f"{exp_name}__{seed}__{int(time.time())}"` to replicate old behavior |
|
| 621 |
+
| `normalize_reward` | renamed to `normalize_advantages`. Note: this always normalized advantages (despite the old name) |
|
| 622 |
+
| `num_ppo_epochs` | renamed to `num_iterations` (default: `1`) |
|
| 623 |
+
| `token_level_kl` | **removed** – KL is now computed only at the sequence level |
|
| 624 |
+
| `dataset_num_proc` | **removed** – it was unused |
|
| 625 |
+
| `num_mini_batches` | renamed to `steps_per_generation` |
|
| 626 |
+
| `total_episodes` | use `max_steps=total_episodes / gradient_accumulation_steps` instead |
|
| 627 |
+
| `local_rollout_forward_batch_size` | **removed** – now automatically set to `per_device_train_batch_size` (or `per_device_eval_batch_size` during evaluation) |
|
| 628 |
+
| `num_sample_generations` | **removed** – use `logging_steps` to control generation logging frequency |
|
| 629 |
+
| `response_length` | renamed to `max_completion_length` (default: `256`) |
|
| 630 |
+
| `stop_token` | **removed** |
|
| 631 |
+
| `stop_token_id` | **removed** – use `processing_class.eos_token_id` instead |
|
| 632 |
+
| `missing_eos_penalty` | **removed** – replicate with a custom reward function checking if `eos_token_id` is in `completion_ids` |
|
| 633 |
+
|
| 634 |
+
Below is a summary of the key changes for [`RLOOTrainer`]:
|
| 635 |
+
|
| 636 |
+
| TRL ≤ 0.21.x | TRL ≥ 0.22.0 |
|
| 637 |
+
| --- | --- |
|
| 638 |
+
| `config` | renamed to `args` |
|
| 639 |
+
| `reward_model` | renamed to `reward_funcs`, which now supports both reward models and custom reward functions |
|
| 640 |
+
| `policy` | renamed to `model` |
|
| 641 |
+
| `ref_policy` | **removed** – the reference model is now created automatically from `model` |
|
| 642 |
+
| `data_collator` | **removed** |
|
tasks/tasksmith-1c108f674e97/tests/source/docs/source/script_utils.md
ADDED
|
@@ -0,0 +1,24 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Scripts Utilities
|
| 2 |
+
|
| 3 |
+
## ScriptArguments
|
| 4 |
+
|
| 5 |
+
[[autodoc]] ScriptArguments
|
| 6 |
+
|
| 7 |
+
## TrlParser
|
| 8 |
+
|
| 9 |
+
[[autodoc]] TrlParser
|
| 10 |
+
- parse_args_and_config
|
| 11 |
+
- parse_args_into_dataclasses
|
| 12 |
+
- set_defaults_with_config
|
| 13 |
+
|
| 14 |
+
## get_dataset
|
| 15 |
+
|
| 16 |
+
[[autodoc]] get_dataset
|
| 17 |
+
|
| 18 |
+
## DatasetConfig
|
| 19 |
+
|
| 20 |
+
[[autodoc]] scripts.utils.DatasetConfig
|
| 21 |
+
|
| 22 |
+
## DatasetMixtureConfig
|
| 23 |
+
|
| 24 |
+
[[autodoc]] DatasetMixtureConfig
|
tasks/tasksmith-1c108f674e97/tests/source/docs/source/sdft_trainer.md
ADDED
|
@@ -0,0 +1,104 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# SDFT
|
| 2 |
+
|
| 3 |
+
Self-Distilled Fine-Tuning (SDFT) is described in [Self-Training with On-Policy Self-Distillation for Language Model Alignment](https://huggingface.co/papers/2601.19897).
|
| 4 |
+
|
| 5 |
+
The TRL implementation adapts SDFT to the experimental trainer API while reusing the shared self-distillation infrastructure also used by SDPO.
|
| 6 |
+
|
| 7 |
+
In the current TRL implementation:
|
| 8 |
+
|
| 9 |
+
- the teacher is the model itself (base weights with adapter disabled for PEFT, or the same model under `no_grad` for non-PEFT); use `sync_ref_model=True` for an EMA teacher
|
| 10 |
+
- the dataset must provide both `prompt` and `privileged_context`
|
| 11 |
+
- `privileged_context` contains only the extra teacher-only information; the trainer combines it with `prompt` to build the teacher prompt
|
| 12 |
+
- `teacher_prompt_template` controls how `prompt` and `privileged_context` are combined into the teacher prompt
|
| 13 |
+
- on-policy generation can use either the student prompt or the teacher-conditioned prompt via `generate_from_teacher`
|
| 14 |
+
- `num_loss_tokens_to_skip` can exclude initial completion tokens from the distillation loss
|
| 15 |
+
- SDFT currently supports text-only training and does not support `use_vllm=True`
|
| 16 |
+
- the shared dataset contract is `prompt` plus `privileged_context`
|
| 17 |
+
|
| 18 |
+
## Usage
|
| 19 |
+
|
| 20 |
+
```python
|
| 21 |
+
from datasets import Dataset
|
| 22 |
+
|
| 23 |
+
from trl.experimental.sdft import SDFTConfig, SDFTTrainer
|
| 24 |
+
|
| 25 |
+
dataset = Dataset.from_dict(
|
| 26 |
+
{
|
| 27 |
+
"prompt": [[{"role": "user", "content": "Solve 2+2."}]],
|
| 28 |
+
"privileged_context": ["Example answer: 4."],
|
| 29 |
+
}
|
| 30 |
+
)
|
| 31 |
+
|
| 32 |
+
training_args = SDFTConfig(
|
| 33 |
+
output_dir="sdft-model",
|
| 34 |
+
distillation_alpha=0.5,
|
| 35 |
+
distillation_topk=5,
|
| 36 |
+
max_completion_length=64,
|
| 37 |
+
)
|
| 38 |
+
|
| 39 |
+
trainer = SDFTTrainer(
|
| 40 |
+
model="Qwen/Qwen2.5-1.5B-Instruct",
|
| 41 |
+
args=training_args,
|
| 42 |
+
train_dataset=dataset,
|
| 43 |
+
)
|
| 44 |
+
trainer.train()
|
| 45 |
+
```
|
| 46 |
+
|
| 47 |
+
To generate from the teacher-conditioned prompt instead of the student prompt, set `generate_from_teacher=True`.
|
| 48 |
+
To customize how the teacher prompt is built, set `teacher_prompt_template` on [`SDFTConfig`].
|
| 49 |
+
|
| 50 |
+
## Expected dataset columns
|
| 51 |
+
|
| 52 |
+
Each example must provide:
|
| 53 |
+
|
| 54 |
+
- `prompt`: the student-facing prompt
|
| 55 |
+
- `privileged_context`: only the extra teacher-only information, such as a demonstration, hint, or privileged feedback
|
| 56 |
+
|
| 57 |
+
Both standard text prompts and conversational prompts are supported by the trainer prompt handling.
|
| 58 |
+
|
| 59 |
+
## Callbacks
|
| 60 |
+
|
| 61 |
+
The trainer emits a small set of callback hooks that are useful for debugging, observability, and tests. These hooks are intended as practical integration points for experimental self-distillation workflows.
|
| 62 |
+
|
| 63 |
+
Shared self-distillation hooks:
|
| 64 |
+
|
| 65 |
+
- `on_self_distillation_batch_prepared`: fired when a self-distillation batch is ready. The payload includes `prompt_ids`, `completion_ids`, and `old_per_token_logps` when importance-sampling clipping inputs are available.
|
| 66 |
+
- `on_generation_batch_built`: fired when a new buffered generation batch is created. The payload includes `generate_every` and `steps_per_generation`.
|
| 67 |
+
|
| 68 |
+
SDFT-specific hook:
|
| 69 |
+
|
| 70 |
+
- `on_generation_prompts_selected`: fired when SDFT chooses the prompt source for on-policy generation. The payload includes the selected `generation_prompts` and the corresponding `generation_prompt_text`.
|
| 71 |
+
|
| 72 |
+
## Example script
|
| 73 |
+
|
| 74 |
+
Use [`trl/experimental/sdft/sdft.py`](https://github.com/huggingface/trl/blob/main/trl/experimental/sdft/sdft.py) to launch SDFT training from the command line. The script supports any causal LM from the Hub, custom local datasets via `--dataset_path`, and PEFT/LoRA via the standard `ModelConfig` flags.
|
| 75 |
+
|
| 76 |
+
```bash
|
| 77 |
+
python trl/experimental/sdft/sdft.py \
|
| 78 |
+
--model_name_or_path Qwen/Qwen3.5-0.8B \
|
| 79 |
+
--dataset_name your-org/your-dataset \
|
| 80 |
+
--output_dir outputs/sdft-qwen3.5-0.8b \
|
| 81 |
+
--per_device_train_batch_size 1 \
|
| 82 |
+
--gradient_accumulation_steps 16 \
|
| 83 |
+
--learning_rate 2e-5 \
|
| 84 |
+
--max_prompt_length 1024 \
|
| 85 |
+
--max_completion_length 512 \
|
| 86 |
+
--generate_from_teacher \
|
| 87 |
+
--sync_ref_model \
|
| 88 |
+
--ref_model_sync_steps 1 \
|
| 89 |
+
--ref_model_mixup_alpha 0.01 \
|
| 90 |
+
--eval_strategy steps \
|
| 91 |
+
--eval_steps 50 \
|
| 92 |
+
--report_to wandb
|
| 93 |
+
```
|
| 94 |
+
|
| 95 |
+
## SDFTConfig
|
| 96 |
+
|
| 97 |
+
[[autodoc]] experimental.sdft.SDFTConfig
|
| 98 |
+
|
| 99 |
+
## SDFTTrainer
|
| 100 |
+
|
| 101 |
+
[[autodoc]] experimental.sdft.SDFTTrainer
|
| 102 |
+
- train
|
| 103 |
+
- save_model
|
| 104 |
+
- push_to_hub
|
tasks/tasksmith-1c108f674e97/tests/source/docs/source/sdpo_trainer.md
ADDED
|
@@ -0,0 +1,108 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# SDPO
|
| 2 |
+
|
| 3 |
+
Self-Distillation Policy Optimization (SDPO) was introduced in [Reinforcement Learning via Self-Distillation](https://huggingface.co/papers/2601.20802) by [Jonas Hübotter](https://huggingface.co/jonhue), Frederike Lübeck, Lejs Behric, [Anton Baumann](https://huggingface.co/antonbaumann), Marco Bagatella, Daniel Marta, Ido Hakimi, Idan Shenfeld, Thomas Kleine Buening, Carlos Guestrin, and Andreas Krause.
|
| 4 |
+
|
| 5 |
+
> Large language models are increasingly post-trained with reinforcement learning in verifiable domains such as code and math. Yet, current methods for reinforcement learning with verifiable rewards (RLVR) learn only from a scalar outcome reward per attempt, creating a severe credit-assignment bottleneck. Many verifiable environments actually provide rich textual feedback, such as runtime errors or judge evaluations, that explain why an attempt failed. We formalize this setting as reinforcement learning with rich feedback and introduce Self-Distillation Policy Optimization (SDPO), which converts tokenized feedback into a dense learning signal without any external teacher or explicit reward model. SDPO treats the current model conditioned on feedback as a self-teacher and distills its feedback-informed next-token predictions back into the policy. In this way, SDPO leverages the model's ability to retrospectively identify its own mistakes in-context. Across scientific reasoning, tool use, and competitive programming on LiveCodeBench v6, SDPO improves sample efficiency and final accuracy over strong RLVR baselines. Notably, SDPO also outperforms baselines in standard RLVR environments that only return scalar feedback by using successful rollouts as implicit feedback for failed attempts. Finally, applying SDPO to individual questions at test time accelerates discovery on difficult binary-reward tasks, achieving the same discovery probability as best-of-k sampling or multi-turn conversations with 3x fewer attempts.
|
| 6 |
+
|
| 7 |
+
The SDPO trainer is built on TRL's experimental shared self-distillation stack. It keeps the online rollout-and-reward training flow, then builds a teacher-conditioned view of the same completions from successful rollouts and optional environment feedback.
|
| 8 |
+
|
| 9 |
+
In the current TRL implementation:
|
| 10 |
+
|
| 11 |
+
- the default SDPO policy loss mode is `distillation_only`
|
| 12 |
+
- `hybrid` mode is also available to combine the base policy loss with the self-distillation loss
|
| 13 |
+
- supported teacher regularization modes are `ema` and `none`
|
| 14 |
+
- `distillation_topk` is only valid when `full_logit_distillation=True`
|
| 15 |
+
- when `full_logit_distillation=False`, SDPO uses token-level reverse KL and requires `distillation_alpha=1.0`
|
| 16 |
+
- environment feedback can be injected into teacher reprompts when the dataset exposes a `privileged_context` column
|
| 17 |
+
|
| 18 |
+
## Expected dataset columns
|
| 19 |
+
|
| 20 |
+
Each example must provide:
|
| 21 |
+
|
| 22 |
+
- `prompt`: the student-facing prompt
|
| 23 |
+
- `privileged_context`: optional privileged text, such as environment feedback, used when `include_environment_feedback=True`
|
| 24 |
+
|
| 25 |
+
## Usage
|
| 26 |
+
|
| 27 |
+
```python
|
| 28 |
+
from datasets import Dataset
|
| 29 |
+
|
| 30 |
+
from trl.experimental.sdpo import SDPOConfig, SDPOTrainer
|
| 31 |
+
|
| 32 |
+
dataset = Dataset.from_dict(
|
| 33 |
+
{
|
| 34 |
+
"prompt": [[{"role": "user", "content": "Solve 2+2."}]],
|
| 35 |
+
"privileged_context": ["Your earlier answer used the wrong format."],
|
| 36 |
+
}
|
| 37 |
+
)
|
| 38 |
+
|
| 39 |
+
training_args = SDPOConfig(
|
| 40 |
+
output_dir="sdpo-model",
|
| 41 |
+
distillation_topk=100, # Top-K logit distillation approximation
|
| 42 |
+
full_logit_distillation=True, # Required for top-K; enables non-reverse divergences
|
| 43 |
+
include_environment_feedback=True, # Use dataset privileged_context for teacher reprompts
|
| 44 |
+
)
|
| 45 |
+
|
| 46 |
+
trainer = SDPOTrainer(
|
| 47 |
+
model="Qwen/Qwen2.5-1.5B-Instruct",
|
| 48 |
+
reward_funcs=reward_func,
|
| 49 |
+
args=training_args,
|
| 50 |
+
train_dataset=dataset,
|
| 51 |
+
)
|
| 52 |
+
trainer.train()
|
| 53 |
+
```
|
| 54 |
+
|
| 55 |
+
SDPO always requires a `prompt` column. To use environment feedback, also include a `privileged_context` column and set `include_environment_feedback=True`. SDPO will use successful rollouts and, when enabled, that text to build teacher reprompts for self-distillation.
|
| 56 |
+
|
| 57 |
+
## Callbacks
|
| 58 |
+
|
| 59 |
+
The trainer emits a small set of callback hooks that are useful for debugging, observability, and tests. These hooks are intended as practical integration points for experimental self-distillation workflows.
|
| 60 |
+
|
| 61 |
+
Shared self-distillation hooks:
|
| 62 |
+
|
| 63 |
+
- `on_self_distillation_batch_prepared`: fired when a self-distillation batch is ready. The payload includes `prompt_ids`, `completion_ids`, and `old_per_token_logps` when importance-sampling clipping inputs are available.
|
| 64 |
+
- `on_generation_batch_built`: fired when a new buffered generation batch is created. The payload includes `generate_every` and `steps_per_generation`.
|
| 65 |
+
|
| 66 |
+
SDPO-specific hook:
|
| 67 |
+
|
| 68 |
+
- `on_teacher_context_built`: fired after SDPO constructs the teacher-conditioned inputs. The payload includes `teacher_input_ids`, `teacher_attention_mask`, `completion_mask`, and `self_distillation_mask`.
|
| 69 |
+
|
| 70 |
+
## Example script
|
| 71 |
+
|
| 72 |
+
Use [`trl/experimental/sdpo/sdpo.py`](https://github.com/huggingface/trl/blob/main/trl/experimental/sdpo/sdpo.py) to launch SDPO training from the command line. The script supports verifiable math rewards, environment feedback via `--feedback_column`, and PEFT/LoRA via the standard `ModelConfig` flags.
|
| 73 |
+
|
| 74 |
+
```bash
|
| 75 |
+
python trl/experimental/sdpo/sdpo.py \
|
| 76 |
+
--model_name_or_path Qwen/Qwen2.5-Math-1.5B-Instruct \
|
| 77 |
+
--dataset_name openai/gsm8k \
|
| 78 |
+
--dataset_config main \
|
| 79 |
+
--output_dir outputs/sdpo-qwen35-2b-gsm8k \
|
| 80 |
+
--learning_rate 5e-5 \
|
| 81 |
+
--dtype bfloat16 \
|
| 82 |
+
--bf16 true \
|
| 83 |
+
--max_completion_length 128 \
|
| 84 |
+
--use_peft \
|
| 85 |
+
--lora_target_modules q_proj k_proj v_proj o_proj gate_proj up_proj down_proj \
|
| 86 |
+
--per_device_train_batch_size 1 \
|
| 87 |
+
--gradient_accumulation_steps 2 \
|
| 88 |
+
--num_generations 8 \
|
| 89 |
+
--generation_batch_size 32 \
|
| 90 |
+
--distillation_alpha 1.0 \
|
| 91 |
+
--full_logit_distillation false \
|
| 92 |
+
--sdpo_policy_loss_mode hybrid \
|
| 93 |
+
--report_to none \
|
| 94 |
+
--eval_strategy steps \
|
| 95 |
+
--eval_steps 1000 \
|
| 96 |
+
--save_strategy no
|
| 97 |
+
```
|
| 98 |
+
|
| 99 |
+
## SDPOConfig
|
| 100 |
+
|
| 101 |
+
[[autodoc]] experimental.sdpo.SDPOConfig
|
| 102 |
+
|
| 103 |
+
## SDPOTrainer
|
| 104 |
+
|
| 105 |
+
[[autodoc]] experimental.sdpo.SDPOTrainer
|
| 106 |
+
- train
|
| 107 |
+
- save_model
|
| 108 |
+
- push_to_hub
|
tasks/tasksmith-1c108f674e97/tests/source/docs/source/sft_trainer.md
ADDED
|
@@ -0,0 +1,349 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# SFT Trainer
|
| 2 |
+
|
| 3 |
+
[](https://huggingface.co/models?other=sft,trl) [](https://github.com/huggingface/smol-course/tree/main/1_instruction_tuning)
|
| 4 |
+
|
| 5 |
+
## Overview
|
| 6 |
+
|
| 7 |
+
TRL supports the Supervised Fine-Tuning (SFT) Trainer for training language models.
|
| 8 |
+
|
| 9 |
+
This post-training method was contributed by [Younes Belkada](https://huggingface.co/ybelkada).
|
| 10 |
+
|
| 11 |
+
## Quick start
|
| 12 |
+
|
| 13 |
+
This example demonstrates how to train a language model using the [`SFTTrainer`] from TRL. We train a [Qwen 3 0.6B](https://huggingface.co/Qwen/Qwen3-0.6B) model on the [Capybara dataset](https://huggingface.co/datasets/trl-lib/Capybara), a compact, diverse multi-turn dataset to benchmark reasoning and generalization.
|
| 14 |
+
|
| 15 |
+
```python
|
| 16 |
+
from trl import SFTTrainer
|
| 17 |
+
from datasets import load_dataset
|
| 18 |
+
|
| 19 |
+
trainer = SFTTrainer(
|
| 20 |
+
model="Qwen/Qwen3-0.6B",
|
| 21 |
+
train_dataset=load_dataset("trl-lib/Capybara", split="train"),
|
| 22 |
+
)
|
| 23 |
+
trainer.train()
|
| 24 |
+
```
|
| 25 |
+
|
| 26 |
+
<iframe src="https://trl-lib-trackio.hf.space/?project=trl-documentation&metrics=train*&sidebar=hidden&runs=sft_qwen3-0.6B_capybara" style="width: 100%; min-width: 300px; max-width: 800px;" height="830" frameBorder="0"></iframe>
|
| 27 |
+
|
| 28 |
+
## Expected dataset type and format
|
| 29 |
+
|
| 30 |
+
SFT supports both [language modeling](dataset_formats#language-modeling) and [prompt-completion](dataset_formats#prompt-completion) datasets. The [`SFTTrainer`] is compatible with both [standard](dataset_formats#standard) and [conversational](dataset_formats#conversational) dataset formats. When provided with a conversational dataset, the trainer will automatically apply the chat template to the dataset.
|
| 31 |
+
|
| 32 |
+
```python
|
| 33 |
+
# Standard language modeling
|
| 34 |
+
{"text": "The sky is blue."}
|
| 35 |
+
|
| 36 |
+
# Conversational language modeling
|
| 37 |
+
{"messages": [{"role": "user", "content": "What color is the sky?"},
|
| 38 |
+
{"role": "assistant", "content": "It is blue."}]}
|
| 39 |
+
|
| 40 |
+
# Standard prompt-completion
|
| 41 |
+
{"prompt": "The sky is",
|
| 42 |
+
"completion": " blue."}
|
| 43 |
+
|
| 44 |
+
# Conversational prompt-completion
|
| 45 |
+
{"prompt": [{"role": "user", "content": "What color is the sky?"}],
|
| 46 |
+
"completion": [{"role": "assistant", "content": "It is blue."}]}
|
| 47 |
+
```
|
| 48 |
+
|
| 49 |
+
If your dataset is not in one of these formats, you can preprocess it to convert it into the expected format. Here is an example with the [FreedomIntelligence/medical-o1-reasoning-SFT](https://huggingface.co/datasets/FreedomIntelligence/medical-o1-reasoning-SFT) dataset:
|
| 50 |
+
|
| 51 |
+
```python
|
| 52 |
+
from datasets import load_dataset
|
| 53 |
+
|
| 54 |
+
dataset = load_dataset("FreedomIntelligence/medical-o1-reasoning-SFT", "en")
|
| 55 |
+
|
| 56 |
+
def preprocess_function(example):
|
| 57 |
+
return {
|
| 58 |
+
"prompt": [{"role": "user", "content": example["Question"]}],
|
| 59 |
+
"completion": [
|
| 60 |
+
{"role": "assistant", "content": f"<think>{example['Complex_CoT']}</think>{example['Response']}"}
|
| 61 |
+
],
|
| 62 |
+
}
|
| 63 |
+
|
| 64 |
+
dataset = dataset.map(preprocess_function, remove_columns=["Question", "Response", "Complex_CoT"])
|
| 65 |
+
print(next(iter(dataset["train"])))
|
| 66 |
+
```
|
| 67 |
+
|
| 68 |
+
```json
|
| 69 |
+
{
|
| 70 |
+
"prompt": [
|
| 71 |
+
{
|
| 72 |
+
"content": "Given the symptoms of sudden weakness in the left arm and leg, recent long-distance travel, and the presence of swollen and tender right lower leg, what specific cardiac abnormality is most likely to be found upon further evaluation that could explain these findings?",
|
| 73 |
+
"role": "user",
|
| 74 |
+
}
|
| 75 |
+
],
|
| 76 |
+
"completion": [
|
| 77 |
+
{
|
| 78 |
+
"content": "<think>Okay, let's see what's going on here. We've got sudden weakness [...] clicks into place!</think>The specific cardiac abnormality most likely to be found in [...] the presence of a PFO facilitating a paradoxical embolism.",
|
| 79 |
+
"role": "assistant",
|
| 80 |
+
}
|
| 81 |
+
],
|
| 82 |
+
}
|
| 83 |
+
```
|
| 84 |
+
|
| 85 |
+
## Looking deeper into the SFT method
|
| 86 |
+
|
| 87 |
+
Supervised Fine-Tuning (SFT) is the simplest and most commonly used method to adapt a language model to a target dataset. The model is trained in a fully supervised fashion using pairs of input and output sequences. The goal is to minimize the negative log-likelihood (NLL) of the target sequence, conditioning on the input.
|
| 88 |
+
|
| 89 |
+
This section breaks down how SFT works in practice, covering the key steps: **preprocessing**, **tokenization** and **loss computation**.
|
| 90 |
+
|
| 91 |
+
### Preprocessing and tokenization
|
| 92 |
+
|
| 93 |
+
During training, each example is expected to contain a **text field** or a **(prompt, completion)** pair, depending on the dataset format. For more details on the expected formats, see [Dataset formats](dataset_formats).
|
| 94 |
+
The [`SFTTrainer`] tokenizes each input using the model's tokenizer. If both prompt and completion are provided separately, they are concatenated before tokenization.
|
| 95 |
+
|
| 96 |
+
### Computing the loss
|
| 97 |
+
|
| 98 |
+

|
| 99 |
+
|
| 100 |
+
The loss used in SFT is the **token-level cross-entropy loss**, defined as:
|
| 101 |
+
|
| 102 |
+
$$
|
| 103 |
+
\mathcal{L}_{\text{SFT}}(\theta) = - \sum_{t=1}^{T} \log p_\theta(y_t \mid y_{<t}),
|
| 104 |
+
$$
|
| 105 |
+
|
| 106 |
+
where \\( y_t \\) is the target token at timestep \\( t \\), and the model is trained to predict the next token given the previous ones. In practice, padding tokens are masked out during loss computation.
|
| 107 |
+
|
| 108 |
+
> [!TIP]
|
| 109 |
+
> The paper [On the Generalization of SFT: A Reinforcement Learning Perspective with Reward Rectification](https://huggingface.co/papers/2508.05629) proposes an alternative loss function, called **Dynamic Fine-Tuning (DFT)**, which aims to improve generalization by rectifying the reward signal. This method can be enabled by setting `loss_type="dft"` in the [`SFTConfig`]. For more details, see [Paper Index - Dynamic Fine-Tuning](paper_index#on-the-generalization-of-sft-a-reinforcement-learning-perspective-with-reward-rectification).
|
| 110 |
+
|
| 111 |
+
> [!TIP]
|
| 112 |
+
> For a memory-efficient variant of the standard loss, set `loss_type="chunked_nll"` in the [`SFTConfig`]. Same math as `"nll"`, but the `lm_head` projection skips ignored-label tokens and the cross-entropy is processed in chunks, so peak activation memory does not scale with the full vocab × seq_len logits tensor. See [Chunked cross-entropy for reducing peak memory usage](reducing_memory_usage#chunked-cross-entropy-for-reducing-peak-memory-usage).
|
| 113 |
+
|
| 114 |
+
### Label shifting and masking
|
| 115 |
+
|
| 116 |
+
During training, the loss is computed using a **one-token shift**: the model is trained to predict each token in the sequence based on all previous tokens. Specifically, the input sequence is shifted right by one position to form the target labels.
|
| 117 |
+
Padding tokens (if present) are ignored in the loss computation by applying an ignore index (default: `-100`) to the corresponding positions. This ensures that the loss focuses only on meaningful, non-padding tokens.
|
| 118 |
+
|
| 119 |
+
## Logged metrics
|
| 120 |
+
|
| 121 |
+
While training and evaluating we record the following reward metrics:
|
| 122 |
+
|
| 123 |
+
* `global_step`: The total number of optimizer steps taken so far.
|
| 124 |
+
* `epoch`: The current epoch number, based on dataset iteration.
|
| 125 |
+
* `num_tokens`: The total number of tokens processed so far.
|
| 126 |
+
* `loss`: The average cross-entropy loss computed over non-masked tokens in the current logging interval.
|
| 127 |
+
* `entropy`: The average entropy of the model's predicted token distribution over non-masked tokens.
|
| 128 |
+
* `mean_token_accuracy`: The proportion of non-masked tokens for which the model’s top-1 prediction matches the ground truth token.
|
| 129 |
+
* `learning_rate`: The current learning rate, which may change dynamically if a scheduler is used.
|
| 130 |
+
* `grad_norm`: The L2 norm of the gradients, computed before gradient clipping.
|
| 131 |
+
|
| 132 |
+
## Customization
|
| 133 |
+
|
| 134 |
+
### Model initialization
|
| 135 |
+
|
| 136 |
+
You can directly pass the kwargs of the [`~transformers.AutoModelForCausalLM.from_pretrained()`] method to the [`SFTConfig`]. For example, if you want to load a model in a different precision, analogous to
|
| 137 |
+
|
| 138 |
+
```python
|
| 139 |
+
model = AutoModelForCausalLM.from_pretrained("Qwen/Qwen3-0.6B", dtype=torch.bfloat16)
|
| 140 |
+
```
|
| 141 |
+
|
| 142 |
+
you can do so by passing the `model_init_kwargs={"dtype": torch.bfloat16}` argument to the [`SFTConfig`].
|
| 143 |
+
|
| 144 |
+
```python
|
| 145 |
+
from trl import SFTConfig
|
| 146 |
+
|
| 147 |
+
training_args = SFTConfig(
|
| 148 |
+
model_init_kwargs={"dtype": torch.bfloat16},
|
| 149 |
+
)
|
| 150 |
+
```
|
| 151 |
+
|
| 152 |
+
Note that all keyword arguments of [`~transformers.AutoModelForCausalLM.from_pretrained()`] are supported.
|
| 153 |
+
|
| 154 |
+
### Packing
|
| 155 |
+
|
| 156 |
+
[`SFTTrainer`] supports _example packing_, where multiple examples are packed in the same input sequence to increase training efficiency. To enable packing, simply pass `packing=True` to the [`SFTConfig`] constructor.
|
| 157 |
+
|
| 158 |
+
```python
|
| 159 |
+
training_args = SFTConfig(packing=True)
|
| 160 |
+
```
|
| 161 |
+
|
| 162 |
+
For more details on packing, see [Packing](reducing_memory_usage#packing).
|
| 163 |
+
|
| 164 |
+
### Train on assistant messages only
|
| 165 |
+
|
| 166 |
+
To train on assistant messages only, use a [conversational](dataset_formats#conversational) dataset and set `assistant_only_loss=True` in the [`SFTConfig`]. This setting ensures that loss is computed **only** on the assistant responses, ignoring user or system messages.
|
| 167 |
+
|
| 168 |
+
```python
|
| 169 |
+
training_args = SFTConfig(assistant_only_loss=True)
|
| 170 |
+
```
|
| 171 |
+
|
| 172 |
+

|
| 173 |
+
|
| 174 |
+
> [!WARNING]
|
| 175 |
+
> This functionality requires the chat template to include `{% generation %}` and `{% endgeneration %}` keywords. For known model families (e.g. Qwen3), TRL automatically patches the template when `assistant_only_loss=True`. See [Chat Templates](chat_templates#training-templates) for the full list of bundled training templates. For other models, check that your chat template includes these keywords. See [HuggingFaceTB/SmolLM3-3B](https://huggingface.co/HuggingFaceTB/SmolLM3-3B/blob/main/chat_template.jinja#L76-L82) for an example.
|
| 176 |
+
|
| 177 |
+
### Train on completion only
|
| 178 |
+
|
| 179 |
+
To train on completion only, use a [prompt-completion](dataset_formats#prompt-completion) dataset. By default, the trainer computes the loss on the completion tokens only, ignoring the prompt tokens. If you want to train on the full sequence, set `completion_only_loss=False` in the [`SFTConfig`].
|
| 180 |
+
|
| 181 |
+
```python
|
| 182 |
+
from trl import SFTConfig, SFTTrainer
|
| 183 |
+
from datasets import load_dataset
|
| 184 |
+
|
| 185 |
+
# Load a prompt-completion dataset; loss is computed on the completion only by default
|
| 186 |
+
dataset = load_dataset("trl-lib/kto-mix-14k", split="train")
|
| 187 |
+
|
| 188 |
+
trainer = SFTTrainer(
|
| 189 |
+
model="Qwen/Qwen2.5-0.5B-Instruct",
|
| 190 |
+
args=SFTConfig(completion_only_loss=True), # True by default for prompt-completion datasets
|
| 191 |
+
train_dataset=dataset,
|
| 192 |
+
)
|
| 193 |
+
trainer.train()
|
| 194 |
+
```
|
| 195 |
+
|
| 196 |
+

|
| 197 |
+
|
| 198 |
+
> [!TIP]
|
| 199 |
+
> Training on completion only is compatible with training on assistant messages only. In this case, use a [conversational](dataset_formats#conversational) [prompt-completion](dataset_formats#prompt-completion) dataset and set `assistant_only_loss=True` in the [`SFTConfig`].
|
| 200 |
+
|
| 201 |
+
### Train adapters with PEFT
|
| 202 |
+
|
| 203 |
+
We support tight integration with 🤗 PEFT library, allowing any user to conveniently train adapters and share them on the Hub, rather than training the entire model.
|
| 204 |
+
|
| 205 |
+
```python
|
| 206 |
+
from datasets import load_dataset
|
| 207 |
+
from trl import SFTTrainer
|
| 208 |
+
from peft import LoraConfig
|
| 209 |
+
|
| 210 |
+
dataset = load_dataset("trl-lib/Capybara", split="train")
|
| 211 |
+
|
| 212 |
+
trainer = SFTTrainer(
|
| 213 |
+
"Qwen/Qwen3-0.6B",
|
| 214 |
+
train_dataset=dataset,
|
| 215 |
+
peft_config=LoraConfig(),
|
| 216 |
+
)
|
| 217 |
+
|
| 218 |
+
trainer.train()
|
| 219 |
+
```
|
| 220 |
+
|
| 221 |
+
You can also continue training your [`~peft.PeftModel`]. For that, first load a `PeftModel` outside [`SFTTrainer`] and pass it directly to the trainer without the `peft_config` argument being passed.
|
| 222 |
+
|
| 223 |
+
```python
|
| 224 |
+
from datasets import load_dataset
|
| 225 |
+
from trl import SFTTrainer
|
| 226 |
+
from peft import AutoPeftModelForCausalLM
|
| 227 |
+
|
| 228 |
+
model = AutoPeftModelForCausalLM.from_pretrained("trl-lib/Qwen3-4B-LoRA", is_trainable=True)
|
| 229 |
+
dataset = load_dataset("trl-lib/Capybara", split="train")
|
| 230 |
+
|
| 231 |
+
trainer = SFTTrainer(
|
| 232 |
+
model=model,
|
| 233 |
+
train_dataset=dataset,
|
| 234 |
+
)
|
| 235 |
+
|
| 236 |
+
trainer.train()
|
| 237 |
+
```
|
| 238 |
+
|
| 239 |
+
> [!TIP]
|
| 240 |
+
> When training adapters, you typically use a higher learning rate (≈1e‑4) since only new parameters are being learned.
|
| 241 |
+
>
|
| 242 |
+
> ```python
|
| 243 |
+
> SFTConfig(learning_rate=1e-4, ...)
|
| 244 |
+
> ```
|
| 245 |
+
|
| 246 |
+
### Train with Liger Kernel
|
| 247 |
+
|
| 248 |
+
Liger Kernel is a collection of Triton kernels for LLM training that boosts multi-GPU throughput by 20%, cuts memory use by 60% (enabling up to 4× longer context), and works seamlessly with tools like FlashAttention, PyTorch FSDP, and DeepSpeed. For more information, see [Liger Kernel Integration](liger_kernel_integration).
|
| 249 |
+
|
| 250 |
+
### Rapid Experimentation for SFT
|
| 251 |
+
|
| 252 |
+
RapidFire AI is an open-source experimentation engine that sits on top of TRL and lets you launch multiple SFT configurations at once, even on a single GPU. Instead of trying configurations sequentially, RapidFire lets you **see all their learning curves earlier, stop underperforming runs, and clone promising ones with new settings in flight** without restarting. For more information, see [RapidFire AI Integration](rapidfire_integration).
|
| 253 |
+
|
| 254 |
+
### Train with Unsloth
|
| 255 |
+
|
| 256 |
+
Unsloth is an open‑source framework for fine‑tuning and reinforcement learning that trains LLMs (like Llama, Mistral, Gemma, DeepSeek, and more) up to 2× faster with up to 70% less VRAM, while providing a streamlined, Hugging Face–compatible workflow for training, evaluation, and deployment. For more information, see [Unsloth Integration](unsloth_integration).
|
| 257 |
+
|
| 258 |
+
## Instruction tuning example
|
| 259 |
+
|
| 260 |
+
**Instruction tuning** teaches a base language model to follow user instructions and engage in conversations. This requires:
|
| 261 |
+
|
| 262 |
+
1. **Chat template**: Defines how to structure conversations into text sequences, including role markers (user/assistant), special tokens, and turn boundaries. Read more about chat templates in [Chat templates](https://huggingface.co/docs/transformers/chat_templating#templates).
|
| 263 |
+
2. **Conversational dataset**: Contains instruction-response pairs
|
| 264 |
+
|
| 265 |
+
This example shows how to transform the [Qwen 3 0.6B Base](https://huggingface.co/Qwen/Qwen3-0.6B-Base) model into an instruction-following model using the [Capybara dataset](https://huggingface.co/datasets/trl-lib/Capybara) and a chat template from [HuggingFaceTB/SmolLM3-3B](https://huggingface.co/HuggingFaceTB/SmolLM3-3B). The SFT Trainer automatically handles tokenizer updates and special token configuration.
|
| 266 |
+
|
| 267 |
+
```python
|
| 268 |
+
from trl import SFTConfig, SFTTrainer
|
| 269 |
+
from datasets import load_dataset
|
| 270 |
+
|
| 271 |
+
trainer = SFTTrainer(
|
| 272 |
+
model="Qwen/Qwen3-0.6B-Base",
|
| 273 |
+
args=SFTConfig(
|
| 274 |
+
output_dir="Qwen3-0.6B-Instruct",
|
| 275 |
+
chat_template_path="HuggingFaceTB/SmolLM3-3B",
|
| 276 |
+
),
|
| 277 |
+
train_dataset=load_dataset("trl-lib/Capybara", split="train"),
|
| 278 |
+
)
|
| 279 |
+
trainer.train()
|
| 280 |
+
```
|
| 281 |
+
|
| 282 |
+
> [!WARNING]
|
| 283 |
+
> Some base models, like those from Qwen, have a predefined chat template in the model's tokenizer. In these cases, it is not necessary to apply [`clone_chat_template()`], as the tokenizer already handles the formatting. However, it is necessary to align the EOS token with the chat template to ensure the model's responses terminate correctly. In these cases, specify `eos_token` in [`SFTConfig`]; for example, for `Qwen/Qwen2.5-1.5B`, one should set `eos_token="<|im_end|>"`.
|
| 284 |
+
|
| 285 |
+
Once trained, your model can now follow instructions and engage in conversations using its new chat template.
|
| 286 |
+
|
| 287 |
+
```python
|
| 288 |
+
>>> from transformers import pipeline
|
| 289 |
+
>>> pipe = pipeline("text-generation", model="Qwen3-0.6B-Instruct/checkpoint-5000")
|
| 290 |
+
>>> prompt = "<|im_start|>user\nWhat is the capital of France? Answer in one word.<|im_end|>\n<|im_start|>assistant\n"
|
| 291 |
+
>>> response = pipe(prompt)
|
| 292 |
+
>>> response[0]["generated_text"]
|
| 293 |
+
'<|im_start|>user\nWhat is the capital of France? Answer in one word.<|im_end|>\n<|im_start|>assistant\nThe capital of France is Paris.'
|
| 294 |
+
```
|
| 295 |
+
|
| 296 |
+
Alternatively, use the structured conversation format (recommended):
|
| 297 |
+
|
| 298 |
+
```python
|
| 299 |
+
>>> prompt = [{"role": "user", "content": "What is the capital of France? Answer in one word."}]
|
| 300 |
+
>>> response = pipe(prompt)
|
| 301 |
+
>>> response[0]["generated_text"]
|
| 302 |
+
[{'role': 'user', 'content': 'What is the capital of France? Answer in one word.'}, {'role': 'assistant', 'content': 'The capital of France is Paris.'}]
|
| 303 |
+
```
|
| 304 |
+
|
| 305 |
+
## Tool Calling with SFT
|
| 306 |
+
|
| 307 |
+
The [`SFTTrainer`] fully supports fine-tuning models with _tool calling_ capabilities. In this case, each dataset example should include:
|
| 308 |
+
|
| 309 |
+
* The conversation messages, including any tool calls (`tool_calls`) and tool responses (`tool` role messages)
|
| 310 |
+
* The list of available tools in the `tools` column, typically provided as JSON schemas
|
| 311 |
+
|
| 312 |
+
For details on the expected dataset structure, see the [Dataset Format — Tool Calling](dataset_formats#tool-calling) section.
|
| 313 |
+
|
| 314 |
+
## Training Vision Language Models
|
| 315 |
+
|
| 316 |
+
[`SFTTrainer`] fully supports training Vision-Language Models (VLMs). To train a VLM, provide a dataset with either an `image` column (single image per sample) or an `images` column (list of images per sample). For more information on the expected dataset structure, see the [Dataset Format — Vision Dataset](dataset_formats#vision-dataset) section.
|
| 317 |
+
An example of such a dataset is the [LLaVA Instruct Mix](https://huggingface.co/datasets/trl-lib/llava-instruct-mix).
|
| 318 |
+
|
| 319 |
+
```python
|
| 320 |
+
from trl import SFTConfig, SFTTrainer
|
| 321 |
+
from datasets import load_dataset
|
| 322 |
+
|
| 323 |
+
trainer = SFTTrainer(
|
| 324 |
+
model="Qwen/Qwen2.5-VL-3B-Instruct",
|
| 325 |
+
args=SFTConfig(max_length=None),
|
| 326 |
+
train_dataset=load_dataset("trl-lib/llava-instruct-mix", split="train"),
|
| 327 |
+
)
|
| 328 |
+
trainer.train()
|
| 329 |
+
```
|
| 330 |
+
|
| 331 |
+
> [!TIP]
|
| 332 |
+
> For VLMs, truncating may remove image tokens, leading to errors during training. To avoid this, set `max_length=None` in the [`SFTConfig`]. This allows the model to process the full sequence length without truncating image tokens.
|
| 333 |
+
>
|
| 334 |
+
> ```python
|
| 335 |
+
> SFTConfig(max_length=None, ...)
|
| 336 |
+
> ```
|
| 337 |
+
>
|
| 338 |
+
> Only use `max_length` when you've verified that truncation won't remove image tokens for the entire dataset.
|
| 339 |
+
|
| 340 |
+
## SFTTrainer
|
| 341 |
+
|
| 342 |
+
[[autodoc]] SFTTrainer
|
| 343 |
+
- train
|
| 344 |
+
- save_model
|
| 345 |
+
- push_to_hub
|
| 346 |
+
|
| 347 |
+
## SFTConfig
|
| 348 |
+
|
| 349 |
+
[[autodoc]] SFTConfig
|
tasks/tasksmith-1c108f674e97/tests/source/docs/source/speeding_up_training.md
ADDED
|
@@ -0,0 +1,204 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Speeding Up Training
|
| 2 |
+
|
| 3 |
+
This guide covers various methods to accelerate training in TRL. Each technique includes minimal examples with links to more comprehensive documentation.
|
| 4 |
+
|
| 5 |
+
## vLLM for fast generation in online methods
|
| 6 |
+
|
| 7 |
+
[Online methods](index#online-methods) such as GRPO or Online DPO require the model to generate completions, which is often a slow process and can significantly impact training time.
|
| 8 |
+
To speed up generation, you can use [vLLM](https://github.com/vllm-project/vllm), a library that enables fast generation through, among other things, PagedAttention. TRL's online trainers support vLLM, greatly improving training speed. For more details, see [vLLM Integration](vllm_integration).
|
| 9 |
+
|
| 10 |
+
To use [vLLM](https://github.com/vllm-project/vllm), first install it using:
|
| 11 |
+
|
| 12 |
+
```bash
|
| 13 |
+
pip install trl[vllm]
|
| 14 |
+
```
|
| 15 |
+
|
| 16 |
+
<hfoptions id="vllm examples">
|
| 17 |
+
<hfoption id="Online DPO">
|
| 18 |
+
|
| 19 |
+
First, start a vLLM server by running:
|
| 20 |
+
|
| 21 |
+
```bash
|
| 22 |
+
trl vllm-serve --model <model_name>
|
| 23 |
+
```
|
| 24 |
+
|
| 25 |
+
Then, run the training script and pass `use_vllm=True` in the training arguments.
|
| 26 |
+
|
| 27 |
+
```python
|
| 28 |
+
from trl.experimental.online_dpo import OnlineDPOConfig
|
| 29 |
+
|
| 30 |
+
training_args = OnlineDPOConfig(..., use_vllm=True, vllm_mode="server")
|
| 31 |
+
```
|
| 32 |
+
|
| 33 |
+
</hfoption>
|
| 34 |
+
<hfoption id="GRPO">
|
| 35 |
+
|
| 36 |
+
First, start a vLLM server by running:
|
| 37 |
+
|
| 38 |
+
```bash
|
| 39 |
+
trl vllm-serve --model <model_name>
|
| 40 |
+
```
|
| 41 |
+
|
| 42 |
+
Then, run the training script and pass `use_vllm=True` in the training arguments.
|
| 43 |
+
|
| 44 |
+
```python
|
| 45 |
+
from trl import GRPOConfig
|
| 46 |
+
|
| 47 |
+
training_args = GRPOConfig(..., use_vllm=True, vllm_mode="server")
|
| 48 |
+
```
|
| 49 |
+
|
| 50 |
+
You can customize the server configuration by passing additional arguments. For more information, see [vLLM integration](vllm_integration).
|
| 51 |
+
|
| 52 |
+
> [!WARNING]
|
| 53 |
+
> When using vLLM, ensure that the GPUs assigned for training and generation are separate to avoid resource conflicts. For instance, if you plan to use 4 GPUs for training and another 4 for vLLM generation, you can specify GPU allocation using `CUDA_VISIBLE_DEVICES`.
|
| 54 |
+
>
|
| 55 |
+
> Set GPUs **0-3** for vLLM generation:
|
| 56 |
+
>
|
| 57 |
+
> ```sh
|
| 58 |
+
> CUDA_VISIBLE_DEVICES=0,1,2,3 trl vllm-serve --model <model_name>
|
| 59 |
+
> ```
|
| 60 |
+
>
|
| 61 |
+
> And GPUs **4-7** for training:
|
| 62 |
+
>
|
| 63 |
+
> ```sh
|
| 64 |
+
> CUDA_VISIBLE_DEVICES=4,5,6,7 accelerate launch train.py
|
| 65 |
+
> ```
|
| 66 |
+
|
| 67 |
+
</hfoption>
|
| 68 |
+
<hfoption id="RLOO">
|
| 69 |
+
|
| 70 |
+
First, start a vLLM server by running:
|
| 71 |
+
|
| 72 |
+
```bash
|
| 73 |
+
trl vllm-serve --model <model_name>
|
| 74 |
+
```
|
| 75 |
+
|
| 76 |
+
Then, run the training script and pass `use_vllm=True` in the training arguments.
|
| 77 |
+
|
| 78 |
+
```python
|
| 79 |
+
from trl import RLOOConfig
|
| 80 |
+
|
| 81 |
+
training_args = RLOOConfig(..., use_vllm=True, vllm_mode="server")
|
| 82 |
+
```
|
| 83 |
+
|
| 84 |
+
You can customize the server configuration by passing additional arguments. For more information, see [vLLM integration](vllm_integration).
|
| 85 |
+
|
| 86 |
+
> [!WARNING]
|
| 87 |
+
> When using vLLM, ensure that the GPUs assigned for training and generation are separate to avoid resource conflicts. For instance, if you plan to use 4 GPUs for training and another 4 for vLLM generation, you can specify GPU allocation using `CUDA_VISIBLE_DEVICES`.
|
| 88 |
+
>
|
| 89 |
+
> Set GPUs **0-3** for vLLM generation:
|
| 90 |
+
>
|
| 91 |
+
> ```sh
|
| 92 |
+
> CUDA_VISIBLE_DEVICES=0,1,2,3 trl vllm-serve --model <model_name>
|
| 93 |
+
> ```
|
| 94 |
+
>
|
| 95 |
+
> And GPUs **4-7** for training:
|
| 96 |
+
>
|
| 97 |
+
> ```sh
|
| 98 |
+
> CUDA_VISIBLE_DEVICES=4,5,6,7 accelerate launch train.py
|
| 99 |
+
> ```
|
| 100 |
+
|
| 101 |
+
</hfoption>
|
| 102 |
+
</hfoptions>
|
| 103 |
+
|
| 104 |
+
## Optimized attention implementations
|
| 105 |
+
|
| 106 |
+
TRL supports various optimized attention implementations that can significantly speed up training while reducing memory usage. You can use either a pre-optimized kernels directly from the [Kernels Hub](kernels_hub) or a manually built attention backend.
|
| 107 |
+
|
| 108 |
+
<hfoptions id="attention examples">
|
| 109 |
+
<hfoption id="Kernels from Hub">
|
| 110 |
+
|
| 111 |
+
You can use pre-optimized attention kernels from the Hub without manual compilation:
|
| 112 |
+
|
| 113 |
+
```python
|
| 114 |
+
from trl import SFTConfig
|
| 115 |
+
|
| 116 |
+
training_args = SFTConfig(..., model_init_kwargs={"attn_implementation": "kernels-community/flash-attn2"})
|
| 117 |
+
```
|
| 118 |
+
|
| 119 |
+
Other options include `kernels-community/vllm-flash-attn3` and `kernels-community/paged-attention`.
|
| 120 |
+
|
| 121 |
+
Optimized attention works across all TRL trainers. For more details, see [Kernels Hub Integration](kernels_hub).
|
| 122 |
+
|
| 123 |
+
</hfoption>
|
| 124 |
+
<hfoption id="Manual build">
|
| 125 |
+
|
| 126 |
+
> [!WARNING]
|
| 127 |
+
> Manually building optimized attention backends is complex and time-consuming. It's never recommended unless absolutely necessary. Consider using Kernels from the Hub instead, as described in the previous section.
|
| 128 |
+
|
| 129 |
+
If you have manually installed an optimized attention backend like Flash Attention 2, you can specify it in the training arguments:
|
| 130 |
+
|
| 131 |
+
```python
|
| 132 |
+
from trl import SFTConfig
|
| 133 |
+
|
| 134 |
+
training_args = SFTConfig(..., model_init_kwargs={"attn_implementation": "flash_attention_2"})
|
| 135 |
+
```
|
| 136 |
+
|
| 137 |
+
</hfoption>
|
| 138 |
+
</hfoptions>
|
| 139 |
+
|
| 140 |
+
## Liger Kernel for memory optimization
|
| 141 |
+
|
| 142 |
+
Liger Kernel is a collection of Triton kernels designed for LLM training that can increase throughput by 20% and reduce memory usage by 60%.
|
| 143 |
+
|
| 144 |
+
<hfoptions id="liger">
|
| 145 |
+
<hfoption id="SFT">
|
| 146 |
+
|
| 147 |
+
```python
|
| 148 |
+
from trl import SFTConfig
|
| 149 |
+
|
| 150 |
+
training_args = SFTConfig(..., use_liger_kernel=True)
|
| 151 |
+
```
|
| 152 |
+
|
| 153 |
+
</hfoption>
|
| 154 |
+
<hfoption id="DPO">
|
| 155 |
+
|
| 156 |
+
```python
|
| 157 |
+
from trl import DPOConfig
|
| 158 |
+
|
| 159 |
+
training_args = DPOConfig(..., use_liger_kernel=True)
|
| 160 |
+
```
|
| 161 |
+
|
| 162 |
+
</hfoption>
|
| 163 |
+
<hfoption id="GRPO">
|
| 164 |
+
|
| 165 |
+
```python
|
| 166 |
+
from trl import GRPOConfig
|
| 167 |
+
|
| 168 |
+
training_args = GRPOConfig(..., use_liger_kernel=True)
|
| 169 |
+
```
|
| 170 |
+
|
| 171 |
+
</hfoption>
|
| 172 |
+
<hfoption id="KTO">
|
| 173 |
+
|
| 174 |
+
```python
|
| 175 |
+
from trl.experimental.kto import KTOConfig
|
| 176 |
+
|
| 177 |
+
training_args = KTOConfig(..., use_liger_kernel=True)
|
| 178 |
+
```
|
| 179 |
+
|
| 180 |
+
</hfoption>
|
| 181 |
+
<hfoption id="GKD">
|
| 182 |
+
|
| 183 |
+
```python
|
| 184 |
+
from trl.experimental.gkd import GKDConfig
|
| 185 |
+
|
| 186 |
+
training_args = GKDConfig(..., use_liger_kernel=True)
|
| 187 |
+
```
|
| 188 |
+
|
| 189 |
+
</hfoption>
|
| 190 |
+
</hfoptions>
|
| 191 |
+
|
| 192 |
+
For more information, see [Liger Kernel Integration](liger_kernel_integration).
|
| 193 |
+
|
| 194 |
+
## Mixed precision training
|
| 195 |
+
|
| 196 |
+
Mixed precision training using bf16 or fp16 can speed up training and reduce memory usage with minimal impact on model quality.
|
| 197 |
+
|
| 198 |
+
```python
|
| 199 |
+
from trl import SFTConfig
|
| 200 |
+
|
| 201 |
+
training_args = SFTConfig(..., bf16=True) # or fp16=True for older GPUs
|
| 202 |
+
```
|
| 203 |
+
|
| 204 |
+
Use `bf16=True` for Ampere GPUs (A100, RTX 30xx) or newer, and `fp16=True` for older GPUs. Mixed precision training is supported across all TRL trainers.
|
tasks/tasksmith-1c108f674e97/tests/source/docs/source/ssd_trainer.md
ADDED
|
@@ -0,0 +1,111 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# SSD
|
| 2 |
+
|
| 3 |
+
Simple Self-Distillation (SSD) is described in [Embarrassingly Simple Self-Distillation Improves Code Generation](https://huggingface.co/papers/2604.01193).
|
| 4 |
+
|
| 5 |
+
SSD samples completions from the model at a training-time temperature and truncation configuration, then fine-tunes on those raw, unverified samples with standard cross-entropy loss. It requires no reward model, verifier, teacher model, or reinforcement learning — only a set of problem prompts and the model itself.
|
| 6 |
+
|
| 7 |
+
In the current TRL implementation:
|
| 8 |
+
|
| 9 |
+
- the model generates completions at a specified training-time temperature (`temperature`) and truncation (`top_k`, `top_p`)
|
| 10 |
+
- the dataset only requires a `prompt` column
|
| 11 |
+
- training uses standard cross-entropy loss on the generated completions
|
| 12 |
+
- empty or single-line stub completions are filtered by default (`filter_empty=True`)
|
| 13 |
+
- the evaluation-time temperature and truncation are set independently at inference time
|
| 14 |
+
- vLLM can be used for faster generation via `use_vllm=True` (see [vLLM integration](vllm_integration))
|
| 15 |
+
|
| 16 |
+
## Usage
|
| 17 |
+
|
| 18 |
+
```python
|
| 19 |
+
from datasets import Dataset
|
| 20 |
+
|
| 21 |
+
from trl.experimental.ssd import SSDConfig, SSDTrainer
|
| 22 |
+
|
| 23 |
+
dataset = Dataset.from_dict(
|
| 24 |
+
{
|
| 25 |
+
"prompt": [
|
| 26 |
+
[{"role": "user", "content": "Write a function to add two numbers."}],
|
| 27 |
+
[{"role": "user", "content": "Write a function to check if a number is prime."}],
|
| 28 |
+
],
|
| 29 |
+
}
|
| 30 |
+
)
|
| 31 |
+
|
| 32 |
+
training_args = SSDConfig(
|
| 33 |
+
output_dir="ssd-model",
|
| 34 |
+
temperature=0.6, # T_train from the paper
|
| 35 |
+
top_k=20, # training-time top-k truncation
|
| 36 |
+
top_p=0.95, # training-time top-p truncation
|
| 37 |
+
max_completion_length=65536,
|
| 38 |
+
learning_rate=5e-6,
|
| 39 |
+
)
|
| 40 |
+
|
| 41 |
+
trainer = SSDTrainer(
|
| 42 |
+
model="Qwen/Qwen3-4B-Instruct",
|
| 43 |
+
args=training_args,
|
| 44 |
+
train_dataset=dataset,
|
| 45 |
+
)
|
| 46 |
+
trainer.train()
|
| 47 |
+
```
|
| 48 |
+
|
| 49 |
+
## Expected dataset columns
|
| 50 |
+
|
| 51 |
+
Each example must provide:
|
| 52 |
+
|
| 53 |
+
- `prompt`: the problem prompt (string or conversational format)
|
| 54 |
+
|
| 55 |
+
No `privileged_context`, reward functions, or teacher model are needed.
|
| 56 |
+
|
| 57 |
+
## Key hyperparameters
|
| 58 |
+
|
| 59 |
+
The paper identifies the following key hyperparameters:
|
| 60 |
+
|
| 61 |
+
- **`temperature`**: training-time sampling temperature (T_train). Higher values create more diverse samples but may include more noise. The paper uses T_train=0.6 with truncation.
|
| 62 |
+
- **`top_k`** and **`top_p`**: training-time truncation parameters (rho_train). These suppress low-probability distractor tails during data synthesis.
|
| 63 |
+
- **T_eval**: the evaluation-time decoding temperature is set independently at inference time. The paper shows that T_train and T_eval compose through an effective temperature T_eff = T_train * T_eval, with a broad optimal band.
|
| 64 |
+
|
| 65 |
+
## Example script
|
| 66 |
+
|
| 67 |
+
Use [`trl/experimental/ssd/ssd.py`](https://github.com/huggingface/trl/blob/main/trl/experimental/ssd/ssd.py) to launch SSD training from the command line. The script supports any causal LM from the Hub, custom local datasets via `--dataset_path`, and PEFT/LoRA via the standard `ModelConfig` flags.
|
| 68 |
+
|
| 69 |
+
```bash
|
| 70 |
+
python trl/experimental/ssd/ssd.py \
|
| 71 |
+
--model_name_or_path Qwen/Qwen3-4B-Instruct-2507 \
|
| 72 |
+
--dataset_name microsoft/rStar-Coder \
|
| 73 |
+
--dataset_config seed_sft \
|
| 74 |
+
--prompt_column question \
|
| 75 |
+
--output_dir outputs/ssd-qwen3-4b \
|
| 76 |
+
--per_device_train_batch_size 1 \
|
| 77 |
+
--gradient_accumulation_steps 32 \
|
| 78 |
+
--learning_rate 5e-6 \
|
| 79 |
+
--lr_scheduler_type cosine \
|
| 80 |
+
--max_prompt_length 1024 \
|
| 81 |
+
--max_completion_length 65536 \
|
| 82 |
+
--temperature 1.6 \
|
| 83 |
+
--top_k 20 \
|
| 84 |
+
--top_p 0.8 \
|
| 85 |
+
--num_train_epochs 1 \
|
| 86 |
+
--bf16 \
|
| 87 |
+
--report_to trackio
|
| 88 |
+
```
|
| 89 |
+
|
| 90 |
+
## Evaluation on LiveCodeBench
|
| 91 |
+
|
| 92 |
+
Use [`trl/experimental/ssd/ssd_eval.py`](https://github.com/huggingface/trl/blob/main/trl/experimental/ssd/ssd_eval.py) to evaluate a base model or an SSD-trained checkpoint on LiveCodeBench v6. The script uses vLLM for generation and LiveCodeBench's official `codegen_metrics` for sandboxed `pass@k` scoring; default decoding parameters match Table 3 of the paper.
|
| 93 |
+
|
| 94 |
+
```bash
|
| 95 |
+
python trl/experimental/ssd/ssd_eval.py \
|
| 96 |
+
--model_name_or_path <path-or-repo> \
|
| 97 |
+
--temperature 1.1 --top_k 20 --top_p 0.8 \
|
| 98 |
+
--n 1 \
|
| 99 |
+
--output_file outputs/lcb_v6.json
|
| 100 |
+
```
|
| 101 |
+
|
| 102 |
+
## SSDConfig
|
| 103 |
+
|
| 104 |
+
[[autodoc]] experimental.ssd.SSDConfig
|
| 105 |
+
|
| 106 |
+
## SSDTrainer
|
| 107 |
+
|
| 108 |
+
[[autodoc]] experimental.ssd.SSDTrainer
|
| 109 |
+
- train
|
| 110 |
+
- save_model
|
| 111 |
+
- push_to_hub
|
tasks/tasksmith-1c108f674e97/tests/source/docs/source/tpo_trainer.md
ADDED
|
@@ -0,0 +1,135 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# TPO Trainer
|
| 2 |
+
|
| 3 |
+
[](https://huggingface.co/models?other=tpo,trl)
|
| 4 |
+
|
| 5 |
+
## Overview
|
| 6 |
+
|
| 7 |
+
Triple Preference Optimization (TPO) was introduced in the paper [Triple Preference Optimization: Achieving Better Alignment using a Single Step Optimization](https://huggingface.co/papers/2405.16681) by Amir Saeidi, Shivanshu Verma, Aswin RRV, and Chitta Baral. TPO enhances the instruction-following and reasoning capabilities of large language models in a single training step, starting from a pre-trained or instruction-tuned model.
|
| 8 |
+
|
| 9 |
+
The abstract from the paper is the following:
|
| 10 |
+
|
| 11 |
+
> Reinforcement Learning with Human Feedback (RLHF) enhances the alignment of Large Language Models (LLMs). However, its limitations have led to the development of Direct Preference Optimization (DPO), an RL-free approach designed to overcome these shortcomings. While studies have shown that DPO improves instruction-following capabilities, it negatively impacts the reasoning ability of LLMs. Additionally, DPO is highly sensitive to judgment noise in preference datasets and the size of the training set. Although several modifications to DPO have been proposed, they still fail to fully resolve these issues. To address these limitations, we propose Triple Preference Optimization (TPO), a new preference learning method designed to enhance both reasoning and instruction-following abilities through one-step optimization. We compare TPO against DPO and its recent variants using state-of-the-art training setups, including both base and instructiontuned models such as Mistral and Llama 3. Our evaluation covers a comprehensive range of chat-based and reasoning benchmarks. The results demonstrate that TPO achieves significant improvements over existing methods without substantially increasing response length across different dataset sizes. Specifically, TPO outperforms DPO and SimPO by up to 7.0% and 7.3% points on Arena-Hard, 12.2% and 13.3% points on MixEval-Hard, 10.4% and 10.1% points on MMLU-Pro, and 19.0% and 19.2% points on GSM8K, respectively. Furthermore, TPO achieves these improvements while requiring less data than DPO.
|
| 12 |
+
|
| 13 |
+
This post-training method was contributed by [Kashif Rasul](https://huggingface.co/kashif).
|
| 14 |
+
|
| 15 |
+
## Quick start
|
| 16 |
+
|
| 17 |
+
This example demonstrates how to train a model using the TPO method. We use the [Qwen 3 0.6B model](https://huggingface.co/Qwen/Qwen3-0.6B) as the base model. TPO requires a *triple-preference* dataset (`prompt`, `chosen`, `rejected`, `reference`) — see [Expected dataset type](#expected-dataset-type-and-format) below.
|
| 18 |
+
|
| 19 |
+
Below is the script to train the model:
|
| 20 |
+
|
| 21 |
+
```python
|
| 22 |
+
# train_tpo.py
|
| 23 |
+
from datasets import load_dataset
|
| 24 |
+
from trl.experimental.tpo import TPOConfig, TPOTrainer
|
| 25 |
+
from transformers import AutoModelForCausalLM, AutoTokenizer
|
| 26 |
+
|
| 27 |
+
model = AutoModelForCausalLM.from_pretrained("Qwen/Qwen3-0.6B")
|
| 28 |
+
tokenizer = AutoTokenizer.from_pretrained("Qwen/Qwen3-0.6B")
|
| 29 |
+
train_dataset = load_dataset("tpo-alignment/triple-preference-ultrafeedback-40K", split="train")
|
| 30 |
+
|
| 31 |
+
training_args = TPOConfig(output_dir="Qwen3-0.6B-TPO")
|
| 32 |
+
trainer = TPOTrainer(model=model, args=training_args, processing_class=tokenizer, train_dataset=train_dataset)
|
| 33 |
+
trainer.train()
|
| 34 |
+
```
|
| 35 |
+
|
| 36 |
+
Execute the script using the following command:
|
| 37 |
+
|
| 38 |
+
```bash
|
| 39 |
+
accelerate launch train_tpo.py
|
| 40 |
+
```
|
| 41 |
+
|
| 42 |
+
## Expected dataset type and format
|
| 43 |
+
|
| 44 |
+
TPO requires a *triple-preference* dataset: each example must contain a `prompt`, a `chosen` (preferred) completion, a `rejected` (dispreferred) completion **and** a `reference` (gold) completion. The [`experimental.tpo.TPOTrainer`] supports both [conversational](dataset_formats#conversational) and [standard](dataset_formats#standard) dataset formats. When provided with a conversational dataset, the trainer will automatically apply the chat template to the dataset.
|
| 45 |
+
|
| 46 |
+
```python
|
| 47 |
+
# Standard format
|
| 48 |
+
triple_preference_example = {
|
| 49 |
+
"prompt": "The sky is",
|
| 50 |
+
"reference": " a beautiful shade of blue.", # gold response (used for the NLL term)
|
| 51 |
+
"chosen": " blue.",
|
| 52 |
+
"rejected": " green.",
|
| 53 |
+
}
|
| 54 |
+
|
| 55 |
+
# Conversational format
|
| 56 |
+
triple_preference_example = {
|
| 57 |
+
"prompt": [{"role": "user", "content": "What color is the sky?"}],
|
| 58 |
+
"reference": [{"role": "assistant", "content": "It is a beautiful shade of blue."}],
|
| 59 |
+
"chosen": [{"role": "assistant", "content": "It is blue."}],
|
| 60 |
+
"rejected": [{"role": "assistant", "content": "It is green."}],
|
| 61 |
+
}
|
| 62 |
+
```
|
| 63 |
+
|
| 64 |
+
The reference response is typically the highest-quality completion available for the prompt; in the original TPO paper it is taken from the response with the highest score in [UltraFeedback](https://huggingface.co/datasets/openbmb/UltraFeedback), with the second-highest used as the chosen completion and the lowest as the rejected completion.
|
| 65 |
+
|
| 66 |
+
## Example script
|
| 67 |
+
|
| 68 |
+
We provide an example script to train a model using the TPO method. The script is available at [`trl/experimental/tpo/tpo.py`](https://github.com/huggingface/trl/blob/main/trl/experimental/tpo/tpo.py).
|
| 69 |
+
|
| 70 |
+
To test the TPO script with the [Qwen 3 0.6B model](https://huggingface.co/Qwen/Qwen3-0.6B) on a triple-preference dataset, run the following command:
|
| 71 |
+
|
| 72 |
+
```bash
|
| 73 |
+
accelerate launch trl/experimental/tpo/tpo.py \
|
| 74 |
+
--model_name_or_path Qwen/Qwen3-0.6B \
|
| 75 |
+
--dataset_name tpo-alignment/triple-preference-ultrafeedback-40K \
|
| 76 |
+
--beta 0.01 \
|
| 77 |
+
--tpo_alpha 1.0 \
|
| 78 |
+
--learning_rate 5e-7 \
|
| 79 |
+
--num_train_epochs 1 \
|
| 80 |
+
--output_dir Qwen3-0.6B-TPO
|
| 81 |
+
```
|
| 82 |
+
|
| 83 |
+
## Looking deeper into the TPO method
|
| 84 |
+
|
| 85 |
+
Triple Preference Optimization (TPO) extends preference-based alignment from pairs to *triples* `(y_gold, y_chosen, y_rejected)`. The model is jointly optimized with two objectives in a single step:
|
| 86 |
+
|
| 87 |
+
1. A **contrastive loss** between the chosen and rejected completions, similar in spirit to DPO/SimPO but computed directly from the policy log-probabilities (no separate reference policy is required).
|
| 88 |
+
2. A **supervised negative log-likelihood (NLL) loss** on the gold (`reference`) completion, weighted by `tpo_alpha`. This term replaces the standalone SFT stage typically required before DPO.
|
| 89 |
+
|
| 90 |
+
The total TPO loss is:
|
| 91 |
+
|
| 92 |
+
$$
|
| 93 |
+
\mathcal{L}_{\mathrm{TPO}}(\theta) = \mathcal{L}_{\mathrm{contrast}}(\theta) + \alpha \cdot \mathcal{L}_{\mathrm{NLL}}(\theta; y_{\text{gold}})
|
| 94 |
+
$$
|
| 95 |
+
|
| 96 |
+
where \\( \alpha \\) is `tpo_alpha` and \\( \mathcal{L}_{\mathrm{contrast}} \\) is selected via `loss_type`.
|
| 97 |
+
|
| 98 |
+
### Loss types
|
| 99 |
+
|
| 100 |
+
| `loss_type=` | Description |
|
| 101 |
+
| --- | --- |
|
| 102 |
+
| `"sigmoid"` (default) | Sigmoid loss on the (sum) log-probability difference between the chosen and rejected completions, as in the original [TPO](https://huggingface.co/papers/2405.16681) paper. |
|
| 103 |
+
| `"hinge"` | Hinge loss on the normalized likelihood from the [SLiC](https://huggingface.co/papers/2305.10425) paper. In this case, `beta` is the reciprocal of the margin. |
|
| 104 |
+
| `"ipo"` | IPO loss from the [IPO](https://huggingface.co/papers/2310.12036) paper, computed on length-normalized log-probabilities. |
|
| 105 |
+
| `"tpo-l"` | Length-normalized TPO variant: uses average per-token log-probabilities and adds a target reward margin `tpo_l_gamma` to the Bradley-Terry objective, in the spirit of [SimPO](https://huggingface.co/papers/2405.14734). |
|
| 106 |
+
|
| 107 |
+
Setting `tpo_alpha=0.0` disables the NLL term entirely (the reference response is then unused, and the corresponding cross-entropy is skipped to save compute).
|
| 108 |
+
|
| 109 |
+
## Logged metrics
|
| 110 |
+
|
| 111 |
+
While training and evaluating we record the following metrics:
|
| 112 |
+
|
| 113 |
+
* `loss`: The total TPO loss (contrastive + `tpo_alpha` × NLL) averaged over the current logging interval.
|
| 114 |
+
* `entropy`: The average entropy of the model's predicted token distribution over completion tokens.
|
| 115 |
+
* `mean_token_accuracy`: The proportion of completion tokens for which the model's top-1 prediction matches the chosen completion.
|
| 116 |
+
* `num_tokens`: The total number of tokens processed so far.
|
| 117 |
+
* `logits/chosen`: The average logit values assigned by the model to the tokens in the chosen completion.
|
| 118 |
+
* `logits/rejected`: The average logit values assigned by the model to the tokens in the rejected completion.
|
| 119 |
+
* `logps/chosen`: The average log-probability assigned by the model to the chosen completion.
|
| 120 |
+
* `logps/rejected`: The average log-probability assigned by the model to the rejected completion.
|
| 121 |
+
* `rewards/chosen`: The average implicit reward computed for the chosen completion, defined as \\( \beta \log \pi_{\theta}(y^{+}\!\mid x) \\).
|
| 122 |
+
* `rewards/rejected`: The average implicit reward computed for the rejected completion, defined as \\( \beta \log \pi_{\theta}(y^{-}\!\mid x) \\).
|
| 123 |
+
* `rewards/margins`: The average implicit reward margin between the chosen and rejected completions.
|
| 124 |
+
* `rewards/accuracies`: The proportion of examples where the implicit reward for the chosen completion is higher than that for the rejected completion.
|
| 125 |
+
|
| 126 |
+
## TPOTrainer
|
| 127 |
+
|
| 128 |
+
[[autodoc]] experimental.tpo.TPOTrainer
|
| 129 |
+
- train
|
| 130 |
+
- save_model
|
| 131 |
+
- push_to_hub
|
| 132 |
+
|
| 133 |
+
## TPOConfig
|
| 134 |
+
|
| 135 |
+
[[autodoc]] experimental.tpo.TPOConfig
|
tasks/tasksmith-1c108f674e97/tests/source/docs/source/trackio_integration.md
ADDED
|
@@ -0,0 +1,67 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Trackio Integration
|
| 2 |
+
|
| 3 |
+
[Trackio](https://huggingface.co/docs/trackio) is a lightweight, free experiment tracking library built on top of **🤗 Datasets** and **🤗 Spaces**. It is the **recommended tracking solution for TRL** and comes natively integrated with all trainers.
|
| 4 |
+
|
| 5 |
+
To enable logging, simply set `report_to="trackio"` in your training config:
|
| 6 |
+
|
| 7 |
+
```python
|
| 8 |
+
from trl import SFTConfig # works with any trainer config (e.g. DPOConfig, GRPOConfig, etc.)
|
| 9 |
+
|
| 10 |
+
training_args = SFTConfig(
|
| 11 |
+
...,
|
| 12 |
+
report_to="trackio", # enable Trackio logging
|
| 13 |
+
)
|
| 14 |
+
```
|
| 15 |
+
|
| 16 |
+
## Organizing Your Experiments with Run Names and Projects
|
| 17 |
+
|
| 18 |
+
By default, Trackio will generate a name to identify each run. However, we highly recommend setting a descriptive `run_name` to make it easier to organize experiments. For example:
|
| 19 |
+
|
| 20 |
+
```python
|
| 21 |
+
from trl import SFTConfig
|
| 22 |
+
|
| 23 |
+
training_args = SFTConfig(
|
| 24 |
+
...,
|
| 25 |
+
report_to="trackio",
|
| 26 |
+
run_name="sft_qwen3-4b_lr2e-5_bs128", # descriptive run name
|
| 27 |
+
)
|
| 28 |
+
```
|
| 29 |
+
|
| 30 |
+
You can also group related experiments by project by setting the following environment variable:
|
| 31 |
+
|
| 32 |
+
```bash
|
| 33 |
+
export TRACKIO_PROJECT="my_project"
|
| 34 |
+
```
|
| 35 |
+
|
| 36 |
+
## Hosting Your Logs on 🤗 Spaces
|
| 37 |
+
|
| 38 |
+
Trackio has local-first design, meaning your logs stay on your machine. If you’d like to host them and deploy a dashboard on **🤗 Spaces**, set:
|
| 39 |
+
|
| 40 |
+
```bash
|
| 41 |
+
export TRACKIO_SPACE_ID="username/space_id"
|
| 42 |
+
```
|
| 43 |
+
|
| 44 |
+
Running the following example:
|
| 45 |
+
|
| 46 |
+
```python
|
| 47 |
+
import os
|
| 48 |
+
from trl import SFTConfig, SFTTrainer
|
| 49 |
+
from datasets import load_dataset
|
| 50 |
+
|
| 51 |
+
os.environ["TRACKIO_SPACE_ID"] = "trl-lib/trackio"
|
| 52 |
+
os.environ["TRACKIO_PROJECT"] = "trl-documentation"
|
| 53 |
+
|
| 54 |
+
trainer = SFTTrainer(
|
| 55 |
+
model="Qwen/Qwen3-0.6B",
|
| 56 |
+
train_dataset=load_dataset("trl-lib/Capybara", split="train"),
|
| 57 |
+
args=SFTConfig(
|
| 58 |
+
report_to="trackio",
|
| 59 |
+
run_name="sft_qwen3-0.6b_capybara",
|
| 60 |
+
),
|
| 61 |
+
)
|
| 62 |
+
trainer.train()
|
| 63 |
+
```
|
| 64 |
+
|
| 65 |
+
will give you a hosted dashboard at https://huggingface.co/spaces/trl-lib/trackio.
|
| 66 |
+
|
| 67 |
+
<iframe src="https://trl-lib-trackio.hf.space/?project=trl-documentation&sidebar=hidden&runs=sft_qwen3-0.6B_capybara" style="width: 100%; min-width: 300px; max-width: 800px;" height="830" frameBorder="0"></iframe>
|
tasks/tasksmith-1c108f674e97/tests/source/docs/source/unsloth_integration.md
ADDED
|
@@ -0,0 +1,125 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Unsloth Integration
|
| 2 |
+
|
| 3 |
+
Unsloth is an open‑source framework for fine‑tuning and reinforcement learning that trains LLMs (like Llama, OpenAI gpt-oss, Mistral, Gemma, DeepSeek, and more) up to 2× faster with up to 80% less VRAM. Unsloth allows [training](https://huggingface.co/docs/trl/en/unsloth_integration#Training), evaluation, running and [deployment](https://huggingface.co/docs/trl/en/unsloth_integration#Saving-the-model) with other inference engines like llama.cpp, Ollama and vLLM.
|
| 4 |
+
|
| 5 |
+
The library provides a streamlined, Hugging Face compatible workflow for training, evaluation, inference and deployment and is fully compatible with [`SFTTrainer`].
|
| 6 |
+
|
| 7 |
+
## Key Features
|
| 8 |
+
|
| 9 |
+
- Training support for all transformer compatible models: Text-to-speech (TTS), multimodal, BERT, RL and more
|
| 10 |
+
- Supports full fine-tuning, pretraining, LoRA, QLoRA, 8-bit training & more
|
| 11 |
+
- Works on Linux, Windows, Colab, Kaggle; NVIDIA GPUs, soon AMD & Intel setups
|
| 12 |
+
- Supports most features TRL supports, including RLHF (GSPO, GRPO, DPO etc.)
|
| 13 |
+
- Hand-written Triton kernels and a manual backprop engine ensure no accuracy degradation (0% approximation error)
|
| 14 |
+
|
| 15 |
+
## Installation
|
| 16 |
+
|
| 17 |
+
### pip install
|
| 18 |
+
|
| 19 |
+
Local Installation (Linux recommended):
|
| 20 |
+
|
| 21 |
+
```sh
|
| 22 |
+
pip install unsloth
|
| 23 |
+
```
|
| 24 |
+
|
| 25 |
+
You can also install `unsloth` according to the [official documentation](https://docs.unsloth.ai/get-started/installing-+-updating). Once installed, you can incorporate unsloth into your workflow in a very simple manner; instead of loading [`~transformers.AutoModelForCausalLM`], you just need to load a `FastLanguageModel` as follows:
|
| 26 |
+
|
| 27 |
+
```python
|
| 28 |
+
import torch
|
| 29 |
+
from trl import SFTConfig, SFTTrainer
|
| 30 |
+
from unsloth import FastLanguageModel
|
| 31 |
+
|
| 32 |
+
max_length = 2048 # Supports automatic RoPE Scaling, so choose any number
|
| 33 |
+
|
| 34 |
+
# Load model
|
| 35 |
+
model, tokenizer = FastLanguageModel.from_pretrained(
|
| 36 |
+
model_name="unsloth/mistral-7b",
|
| 37 |
+
max_seq_length=max_length,
|
| 38 |
+
dtype="auto", # For auto-detection. Float16 for Tesla T4, V100, Bfloat16 for Ampere+
|
| 39 |
+
load_in_4bit=True, # Use 4bit quantization to reduce memory usage. Can be False
|
| 40 |
+
)
|
| 41 |
+
|
| 42 |
+
# Do model patching and add fast LoRA weights
|
| 43 |
+
model = FastLanguageModel.get_peft_model(
|
| 44 |
+
model,
|
| 45 |
+
r=16,
|
| 46 |
+
target_modules=[
|
| 47 |
+
"q_proj",
|
| 48 |
+
"k_proj",
|
| 49 |
+
"v_proj",
|
| 50 |
+
"o_proj",
|
| 51 |
+
"gate_proj",
|
| 52 |
+
"up_proj",
|
| 53 |
+
"down_proj",
|
| 54 |
+
],
|
| 55 |
+
lora_alpha=16,
|
| 56 |
+
lora_dropout=0, # Dropout = 0 is currently optimized
|
| 57 |
+
bias="none", # Bias = "none" is currently optimized
|
| 58 |
+
use_gradient_checkpointing=True,
|
| 59 |
+
random_state=3407,
|
| 60 |
+
)
|
| 61 |
+
|
| 62 |
+
training_args = SFTConfig(output_dir="./output", max_length=max_length)
|
| 63 |
+
|
| 64 |
+
trainer = SFTTrainer(
|
| 65 |
+
model=model,
|
| 66 |
+
args=training_args,
|
| 67 |
+
train_dataset=dataset,
|
| 68 |
+
)
|
| 69 |
+
trainer.train()
|
| 70 |
+
```
|
| 71 |
+
|
| 72 |
+
The saved model is fully compatible with Hugging Face's transformers library. Learn more about unsloth in their [official repository](https://github.com/unslothai/unsloth).
|
| 73 |
+
|
| 74 |
+
### Docker Install
|
| 75 |
+
|
| 76 |
+
```sh
|
| 77 |
+
docker run -d -e JUPYTER_PASSWORD="mypassword" \
|
| 78 |
+
-p 8888:8888 -p 2222:22 \
|
| 79 |
+
-v $(pwd)/work:/workspace/work \
|
| 80 |
+
--gpus all \
|
| 81 |
+
unsloth/unsloth
|
| 82 |
+
```
|
| 83 |
+
|
| 84 |
+
Access Jupyter Lab at ```http://localhost:8888``` and start fine-tuning!
|
| 85 |
+
|
| 86 |
+
## Training
|
| 87 |
+
|
| 88 |
+
These are some core settings you can toggle before training:
|
| 89 |
+
|
| 90 |
+
- ```max_seq_length = 2048``` – Controls context length. While Llama-3 supports 8192, we recommend 2048 for testing. Unsloth enables 4× longer context fine-tuning.
|
| 91 |
+
- ```dtype = "auto"``` – For auto-detection; use torch.float16 or torch.bfloat16 for newer GPUs.
|
| 92 |
+
- ```load_in_4bit = True``` – Enables 4-bit quantization, reducing memory use 4× for fine-tuning. Disabling it allows for LoRA 16-bit fine-tuning to be enabled.
|
| 93 |
+
- To enable full fine-tuning (FFT), set ```full_finetuning = True```. For 8-bit fine-tuning, set ```load_in_8bit = True```. Note: Only one training method can be set to True at a time.
|
| 94 |
+
|
| 95 |
+
For more information on configuring Unsloth's hyperparameters and features, read their [documentation guide here](https://docs.unsloth.ai/get-started/fine-tuning-llms-guide).
|
| 96 |
+
|
| 97 |
+
## Saving the model
|
| 98 |
+
|
| 99 |
+
Unsloth allows you to directly save the finetuned model as a small file called a LoRA adapter. You can instead push to the Hugging Face hub as well if you want to upload your model! Remember to get a [Hugging Face token](https://huggingface.co/settings/tokens) and add your token!
|
| 100 |
+
|
| 101 |
+
### Saving to GGUF
|
| 102 |
+
|
| 103 |
+
To save to GGUF, Unsloth uses llama.cpp. To save locally:
|
| 104 |
+
|
| 105 |
+
```python
|
| 106 |
+
model.save_pretrained_gguf("directory", tokenizer, quantization_method = "q4_k_m")
|
| 107 |
+
model.save_pretrained_gguf("directory", tokenizer, quantization_method = "q8_0")
|
| 108 |
+
model.save_pretrained_gguf("directory", tokenizer, quantization_method = "f16")
|
| 109 |
+
```
|
| 110 |
+
|
| 111 |
+
To push to the hub:
|
| 112 |
+
|
| 113 |
+
```python
|
| 114 |
+
model.push_to_hub_gguf("hf_username/directory", tokenizer, quantization_method = "q4_k_m")
|
| 115 |
+
model.push_to_hub_gguf("hf_username/directory", tokenizer, quantization_method = "q8_0")
|
| 116 |
+
```
|
| 117 |
+
|
| 118 |
+
### Saving to vLLM
|
| 119 |
+
|
| 120 |
+
To save to 16-bit for vLLM, use:
|
| 121 |
+
|
| 122 |
+
```python
|
| 123 |
+
model.save_pretrained_merged("model", tokenizer, save_method = "merged_16bit",)
|
| 124 |
+
model.push_to_hub_merged("hf/model", tokenizer, save_method = "merged_16bit", token = "")
|
| 125 |
+
```
|
tasks/tasksmith-1c108f674e97/tests/source/docs/source/use_model.md
ADDED
|
@@ -0,0 +1,58 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Use model after training
|
| 2 |
+
|
| 3 |
+
Once you have trained a model using either the SFTTrainer, PPOTrainer, or DPOTrainer, you will have a fine-tuned model that can be used for text generation. In this section, we'll walk through the process of loading the fine-tuned model and generating text. If you need to run an inference server with the trained model, you can explore libraries such as [`text-generation-inference`](https://github.com/huggingface/text-generation-inference).
|
| 4 |
+
|
| 5 |
+
## Load and Generate
|
| 6 |
+
|
| 7 |
+
If you have fine-tuned a model fully, meaning without the use of PEFT you can simply load it like any other language model in transformers. E.g. the value head that was trained during the PPO training is no longer needed and if you load the model with the original transformer class it will be ignored:
|
| 8 |
+
|
| 9 |
+
```python
|
| 10 |
+
from transformers import AutoTokenizer, AutoModelForCausalLM
|
| 11 |
+
|
| 12 |
+
model_name_or_path = "Qwen/Qwen3-0.6B" #path/to/your/model/or/name/on/hub
|
| 13 |
+
device = "cpu" # or "cuda" if you have a GPU
|
| 14 |
+
|
| 15 |
+
model = AutoModelForCausalLM.from_pretrained(model_name_or_path).to(device)
|
| 16 |
+
tokenizer = AutoTokenizer.from_pretrained(model_name_or_path)
|
| 17 |
+
|
| 18 |
+
inputs = tokenizer.encode("This movie was really", return_tensors="pt").to(device)
|
| 19 |
+
outputs = model.generate(inputs)
|
| 20 |
+
print(tokenizer.decode(outputs[0]))
|
| 21 |
+
```
|
| 22 |
+
|
| 23 |
+
Alternatively you can also use the pipeline:
|
| 24 |
+
|
| 25 |
+
```python
|
| 26 |
+
from transformers import pipeline
|
| 27 |
+
|
| 28 |
+
model_name_or_path = "Qwen/Qwen3-0.6B" #path/to/your/model/or/name/on/hub
|
| 29 |
+
pipe = pipeline("text-generation", model=model_name_or_path)
|
| 30 |
+
print(pipe("This movie was really")[0]["generated_text"])
|
| 31 |
+
```
|
| 32 |
+
|
| 33 |
+
## Use Adapters PEFT
|
| 34 |
+
|
| 35 |
+
```python
|
| 36 |
+
from peft import PeftConfig, PeftModel
|
| 37 |
+
from transformers import AutoModelForCausalLM, AutoTokenizer
|
| 38 |
+
|
| 39 |
+
base_model_name = "Qwen/Qwen3-0.6B" #path/to/your/model/or/name/on/hub
|
| 40 |
+
adapter_model_name = "path/to/my/adapter"
|
| 41 |
+
|
| 42 |
+
model = AutoModelForCausalLM.from_pretrained(base_model_name)
|
| 43 |
+
model = PeftModel.from_pretrained(model, adapter_model_name)
|
| 44 |
+
|
| 45 |
+
tokenizer = AutoTokenizer.from_pretrained(base_model_name)
|
| 46 |
+
```
|
| 47 |
+
|
| 48 |
+
You can also merge the adapters into the base model so you can use the model like a normal transformers model, however the checkpoint will be significantly bigger:
|
| 49 |
+
|
| 50 |
+
```python
|
| 51 |
+
model = AutoModelForCausalLM.from_pretrained(base_model_name)
|
| 52 |
+
model = PeftModel.from_pretrained(model, adapter_model_name)
|
| 53 |
+
|
| 54 |
+
model = model.merge_and_unload()
|
| 55 |
+
model.save_pretrained("merged_adapters")
|
| 56 |
+
```
|
| 57 |
+
|
| 58 |
+
Once you have the model loaded and either merged the adapters or keep them separately on top you can run generation as with a normal model outlined above.
|
tasks/tasksmith-1c108f674e97/tests/source/docs/source/vllm_integration.md
ADDED
|
@@ -0,0 +1,430 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# vLLM Integration
|
| 2 |
+
|
| 3 |
+
This document will guide you through the process of using vLLM with TRL for faster generation in online methods like GRPO and Online DPO. We first summarize a tl;dr on how to use vLLM with TRL, and then we will go into the details of how it works under the hood.
|
| 4 |
+
|
| 5 |
+
> [!WARNING]
|
| 6 |
+
> TRL currently only supports vLLM versions from `0.12.0` to `0.18.0`. Please ensure you have a version in this range installed to avoid compatibility issues.
|
| 7 |
+
|
| 8 |
+
> [!TIP]
|
| 9 |
+
> The following trainers currently support generation with vLLM:
|
| 10 |
+
>
|
| 11 |
+
> - [`GRPOTrainer`]
|
| 12 |
+
> - [`RLOOTrainer`]
|
| 13 |
+
> - [`experimental.nash_md.NashMDTrainer`]
|
| 14 |
+
> - [`experimental.online_dpo.OnlineDPOTrainer`]
|
| 15 |
+
> - [`experimental.xpo.XPOTrainer`]
|
| 16 |
+
|
| 17 |
+
## 🚀 How can I use vLLM with TRL to speed up training?
|
| 18 |
+
|
| 19 |
+
💡 **Note**: Resources required for this specific example: a single node with 8 GPUs.
|
| 20 |
+
|
| 21 |
+
> [!WARNING]
|
| 22 |
+
> When using vLLM with TRL, the **vLLM server** and the **trainer** must run on **separate CUDA devices** to prevent conflicts.
|
| 23 |
+
> For guidance on configuring this properly, see [Modes of using vLLM during training](#modes-of-using-vllm-during-training).
|
| 24 |
+
|
| 25 |
+
First, install vLLM using the following command:
|
| 26 |
+
|
| 27 |
+
```bash
|
| 28 |
+
pip install "trl[vllm]"
|
| 29 |
+
```
|
| 30 |
+
|
| 31 |
+
Then run the server on specific GPUs (e.g., GPUs 0-3):
|
| 32 |
+
|
| 33 |
+
```sh
|
| 34 |
+
CUDA_VISIBLE_DEVICES=0,1,2,3 trl vllm-serve --model Qwen/Qwen2.5-7B --tensor-parallel-size 4
|
| 35 |
+
```
|
| 36 |
+
|
| 37 |
+
Once the server is running, you can use it to generate completions for training. In the example below, we are using the different supported trainers using the vLLM server for generation. The `--tensor-parallel-size` and `--data-parallel-size` arguments control how the model and data are sharded across GPUs.
|
| 38 |
+
|
| 39 |
+
In this example, we shard one model across 4 GPUs with tensor parallelism. Then, run the training script on different GPUs (e.g., GPUs 4-7) by passing `use_vllm=True` in the training arguments as follows:
|
| 40 |
+
|
| 41 |
+
Sample of a simple `train.py` script:
|
| 42 |
+
|
| 43 |
+
<hfoptions id="vllm examples">
|
| 44 |
+
<hfoption id="GRPO">
|
| 45 |
+
|
| 46 |
+
```python
|
| 47 |
+
from datasets import load_dataset
|
| 48 |
+
from trl import GRPOTrainer, GRPOConfig
|
| 49 |
+
from trl.rewards import accuracy_reward
|
| 50 |
+
|
| 51 |
+
dataset = load_dataset("trl-lib/DeepMath-103K", split="train")
|
| 52 |
+
|
| 53 |
+
trainer = GRPOTrainer(
|
| 54 |
+
model="Qwen/Qwen2.5-7B",
|
| 55 |
+
args=GRPOConfig(use_vllm=True, vllm_mode="server"),
|
| 56 |
+
reward_funcs=accuracy_reward,
|
| 57 |
+
train_dataset=dataset,
|
| 58 |
+
)
|
| 59 |
+
|
| 60 |
+
trainer.train()
|
| 61 |
+
```
|
| 62 |
+
|
| 63 |
+
</hfoption>
|
| 64 |
+
<hfoption id="OnlineDPO">
|
| 65 |
+
|
| 66 |
+
```python
|
| 67 |
+
from datasets import load_dataset
|
| 68 |
+
from trl.experimental.online_dpo import OnlineDPOConfig, OnlineDPOTrainer
|
| 69 |
+
from trl.rewards import accuracy_reward
|
| 70 |
+
|
| 71 |
+
dataset = load_dataset("trl-lib/DeepMath-103K", split="train")
|
| 72 |
+
|
| 73 |
+
trainer = OnlineDPOTrainer(
|
| 74 |
+
model="Qwen/Qwen2.5-7B",
|
| 75 |
+
args=OnlineDPOConfig(use_vllm=True, vllm_mode="server"),
|
| 76 |
+
reward_funcs=accuracy_reward,
|
| 77 |
+
train_dataset=dataset,
|
| 78 |
+
)
|
| 79 |
+
|
| 80 |
+
trainer.train()
|
| 81 |
+
```
|
| 82 |
+
|
| 83 |
+
</hfoption>
|
| 84 |
+
<hfoption id="NashMD">
|
| 85 |
+
|
| 86 |
+
```python
|
| 87 |
+
from datasets import load_dataset
|
| 88 |
+
from trl.experimental.nash_md import NashMDConfig, NashMDTrainer
|
| 89 |
+
from trl.rewards import accuracy_reward
|
| 90 |
+
|
| 91 |
+
dataset = load_dataset("trl-lib/DeepMath-103K", split="train")
|
| 92 |
+
|
| 93 |
+
trainer = NashMDTrainer(
|
| 94 |
+
model="Qwen/Qwen2.5-7B",
|
| 95 |
+
args=NashMDConfig(use_vllm=True, vllm_mode="server"),
|
| 96 |
+
reward_funcs=accuracy_reward,
|
| 97 |
+
train_dataset=dataset,
|
| 98 |
+
)
|
| 99 |
+
|
| 100 |
+
trainer.train()
|
| 101 |
+
```
|
| 102 |
+
|
| 103 |
+
</hfoption>
|
| 104 |
+
<hfoption id="XPO">
|
| 105 |
+
|
| 106 |
+
```python
|
| 107 |
+
from datasets import load_dataset
|
| 108 |
+
from trl.experimental.xpo import XPOTrainer, XPOConfig
|
| 109 |
+
from trl.rewards import accuracy_reward
|
| 110 |
+
|
| 111 |
+
dataset = load_dataset("trl-lib/DeepMath-103K", split="train")
|
| 112 |
+
|
| 113 |
+
trainer = XPOTrainer(
|
| 114 |
+
model="Qwen/Qwen2.5-7B",
|
| 115 |
+
args=XPOConfig(use_vllm=True, vllm_mode="server"),
|
| 116 |
+
reward_funcs=accuracy_reward,
|
| 117 |
+
train_dataset=dataset,
|
| 118 |
+
)
|
| 119 |
+
|
| 120 |
+
trainer.train()
|
| 121 |
+
```
|
| 122 |
+
|
| 123 |
+
</hfoption>
|
| 124 |
+
<hfoption id="RLOO">
|
| 125 |
+
|
| 126 |
+
```python
|
| 127 |
+
from datasets import load_dataset
|
| 128 |
+
from trl import RLOOTrainer, RLOOConfig
|
| 129 |
+
from trl.rewards import accuracy_reward
|
| 130 |
+
|
| 131 |
+
dataset = load_dataset("trl-lib/DeepMath-103K", split="train")
|
| 132 |
+
|
| 133 |
+
trainer = RLOOTrainer(
|
| 134 |
+
model="Qwen/Qwen2.5-7B",
|
| 135 |
+
args=RLOOConfig(use_vllm=True, vllm_mode="server"),
|
| 136 |
+
reward_funcs=accuracy_reward,
|
| 137 |
+
train_dataset=dataset,
|
| 138 |
+
)
|
| 139 |
+
|
| 140 |
+
trainer.train()
|
| 141 |
+
```
|
| 142 |
+
|
| 143 |
+
</hfoption>
|
| 144 |
+
</hfoptions>
|
| 145 |
+
|
| 146 |
+
And the train command on separate GPUs from the server:
|
| 147 |
+
|
| 148 |
+
```sh
|
| 149 |
+
CUDA_VISIBLE_DEVICES=4,5,6,7 accelerate launch train.py
|
| 150 |
+
```
|
| 151 |
+
|
| 152 |
+
## Why using vLLM?
|
| 153 |
+
|
| 154 |
+
### 🎬 Flashback: Why do we need to use vLLM in online methods?
|
| 155 |
+
|
| 156 |
+
Online methods like GRPO or Online DPO require the model to generate completions during training, which are then used to compute reward signals. However, generation can be extremely time-consuming, especially with large or reasoning models. In the default setup (without vLLM), completions are generated using the [(unwrapped) model's `generate` method](https://github.com/huggingface/trl/blob/f3e8c2304428ef16e9ae5de9e5741ed84d533b7b/trl/trainer/grpo_trainer.py#L965C39-L965C66). This approach quickly becomes a major bottleneck — generation is slow and inefficient, particularly for large batches or models. As a result, training times increase significantly, and overall efficiency drops. To address this, we turn to vLLM, which enables much faster and more scalable generation, helping eliminate this bottleneck in online methods.
|
| 157 |
+
|
| 158 |
+
### 🤔 How does vLLM solve the slow generation issue?
|
| 159 |
+
|
| 160 |
+
If you've ever done autoregressive decoder training, you know all the input tokens to the LLM produce their attention key and value tensors, and these tensors are kept in GPU memory to later generate subsequent tokens based on them. These cached key and value tensors are often referred to as the KV cache. However, storing the KV cache occupies a lot of memory, so vLLM uses a technique called **PagedAttention** to solve this problem. PagedAttention, which is inspired by the OS’s virtual memory concept, stores continuous keys and values in **non-contiguous memory space**, which is much more efficient. The details of this are beyond the scope of this document, but in short, it allows the model to store the keys and values in a more efficient way, reducing the memory footprint and speeding up the generation process. If you are interested, make sure to check out the [vLLM PagedAttention](https://blog.vllm.ai/2023/06/20/vllm.html) for more details.
|
| 161 |
+
|
| 162 |
+
## How vLLM Works (Under the Hood) 🔍
|
| 163 |
+
|
| 164 |
+
### 🤔 What exactly happens when you run `trl vllm-serve --model <model_name>`?
|
| 165 |
+
|
| 166 |
+
When you run for example
|
| 167 |
+
|
| 168 |
+
```sh
|
| 169 |
+
CUDA_VISIBLE_DEVICES=0,1,2,3 trl vllm-serve --model Qwen/Qwen2.5-7B --tensor-parallel-size 4
|
| 170 |
+
```
|
| 171 |
+
|
| 172 |
+
1. vLLM first spawns multiple workers to handle incoming requests in parallel. The number of workers is determined by multiplying the `--tensor-parallel-size` and `--data-parallel-size` values. In this example, it spawns 4 workers (4 × 1).
|
| 173 |
+
Each worker operates independently and processes a chunk of the incoming requests — which are basically the prompts sent to the server for generation.
|
| 174 |
+
|
| 175 |
+
2. Once the incoming requests (prompts) are distributed across the workers, the model starts generating completions. Internally, the model’s weights are split across multiple GPUs based on the `--tensor-parallel-size` argument — this is how tensor parallelism is handled.
|
| 176 |
+
|
| 177 |
+
3. Although the GPUs process requests independently and in parallel, they still need to communicate with each other. Remember that each GPU handles only a slice of the incoming prompts (for example, with 4 GPUs and 8 prompts using `--tensor-parallel-size=4`, each GPU participates in serving the full model).
|
| 178 |
+
This GPU-to-GPU communication is managed efficiently by NVIDIA’s NCCL library. The communication mainly ensures that each GPU gets its correct portion of the incoming requests — it’s lightweight and doesn’t interfere with generation itself.
|
| 179 |
+
Separately, the number of completions to generate per prompt is controlled by the `num_generations` setting in the GRPO config. For instance, if you set `num_generations=2` (like in the picture above), each prompt will have 2 completions. So, with 8 prompts and `num_generations=2`, you would end up with 16 completions total — regardless of the number of GPUs or parallelism settings.
|
| 180 |
+
|
| 181 |
+
### 🥸 More detail on what happens under the hood when running the server
|
| 182 |
+
|
| 183 |
+
- The vLLM server starts by running the command: `trl vllm-serve --model Qwen/Qwen2.5-7B`.
|
| 184 |
+
- Once the server is running, it generates completions based on requests from the client (trainer) using `vllm_client.generate` [these lines](https://github.com/huggingface/trl/blob/cc044e35b285be7dc062764b3364e1e684db4c7c/trl/trainer/grpo_trainer.py#L1025-L1035).
|
| 185 |
+
- The client (trainer) then requests these completions from the server.
|
| 186 |
+
- These completions are used to compute the reward signal.
|
| 187 |
+
- Based on the reward signal and the model’s output, the loss is computed, and the backward pass is performed to update the model’s weights.
|
| 188 |
+
- **Note**: The server only handles completion generation — it doesn’t train the model. Therefore, the model’s weights aren’t updated on the server. Once the backward pass is complete, the client sends the updated weights to the server using `vllm_client.update_named_param(name, param.data)`.
|
| 189 |
+
|
| 190 |
+
When using vLLM, ensure the GPUs assigned for training and generation are separate to avoid NCCL communication conflicts. If you do not set the `CUDA_VISIBLE_DEVICES` environment variable, the training script will use all available GPUs by default, which may lead to device conflicts. Starting from TRL next release after v0.19.1, the code automatically detects and prevents same-device usage, raising a error at the vllm server process:
|
| 191 |
+
|
| 192 |
+
```log
|
| 193 |
+
RuntimeError: Attempting to use the same CUDA device for multiple distinct roles/ranks within the same communicator.
|
| 194 |
+
Ensure that trainer is using different devices than vLLM server.
|
| 195 |
+
```
|
| 196 |
+
|
| 197 |
+
For example, if you want to use GPUs 4–7 for training while the server runs on GPUs 0-3, set:
|
| 198 |
+
|
| 199 |
+
```sh
|
| 200 |
+
CUDA_VISIBLE_DEVICES=4,5,6,7 accelerate launch train.py
|
| 201 |
+
```
|
| 202 |
+
|
| 203 |
+
## Advanced usage
|
| 204 |
+
|
| 205 |
+
### 🍷 More customization options with vLLM?
|
| 206 |
+
|
| 207 |
+
You can customize the server configuration by passing additional arguments.
|
| 208 |
+
|
| 209 |
+
```txt
|
| 210 |
+
$ trl vllm-serve --help
|
| 211 |
+
usage: trl vllm-serve [-h] --model MODEL [--revision REVISION] [--tensor_parallel_size TENSOR_PARALLEL_SIZE] [--data_parallel_size DATA_PARALLEL_SIZE] [--host HOST]
|
| 212 |
+
[--port PORT] [--gpu_memory_utilization GPU_MEMORY_UTILIZATION] [--dtype DTYPE] [--max_model_len MAX_MODEL_LEN]
|
| 213 |
+
[--enable_prefix_caching ENABLE_PREFIX_CACHING] [--enforce_eager [ENFORCE_EAGER]] [--kv_cache_dtype KV_CACHE_DTYPE]
|
| 214 |
+
[--trust_remote_code [TRUST_REMOTE_CODE]] [--log_level LOG_LEVEL] [--vllm_model_impl VLLM_MODEL_IMPL]
|
| 215 |
+
|
| 216 |
+
options:
|
| 217 |
+
-h, --help show this help message and exit
|
| 218 |
+
--model MODEL Model name or path to load the model from. (default: None)
|
| 219 |
+
--revision REVISION Revision to use for the model. If not specified, the default branch will be used. (default: None)
|
| 220 |
+
--tensor_parallel_size TENSOR_PARALLEL_SIZE, --tensor-parallel-size TENSOR_PARALLEL_SIZE
|
| 221 |
+
Number of tensor parallel workers to use. (default: 1)
|
| 222 |
+
--data_parallel_size DATA_PARALLEL_SIZE, --data-parallel-size DATA_PARALLEL_SIZE
|
| 223 |
+
Number of data parallel workers to use. For dense models, keep this at 1. Starting from vLLM `0.14.0`, setting
|
| 224 |
+
this above `1` for dense models is no longer supported/useful and will error out (see vLLM PR #30739).
|
| 225 |
+
(default: 1)
|
| 226 |
+
--host HOST Host address to run the server on. (default: 0.0.0.0)
|
| 227 |
+
--port PORT Port to run the server on. (default: 8000)
|
| 228 |
+
--gpu_memory_utilization GPU_MEMORY_UTILIZATION, --gpu-memory-utilization GPU_MEMORY_UTILIZATION
|
| 229 |
+
Ratio (between 0 and 1) of GPU memory to reserve for the model weights, activations, and KV cache on the device dedicated to generation
|
| 230 |
+
powered by vLLM. Higher values will increase the KV cache size and thus improve the model's throughput. However, if the value is too high,
|
| 231 |
+
it may cause out-of-memory (OOM) errors during initialization. (default: 0.9)
|
| 232 |
+
--dtype DTYPE Data type to use for vLLM generation. If set to 'auto', the data type will be automatically determined based on the model configuration.
|
| 233 |
+
Find the supported values in the vLLM documentation. (default: auto)
|
| 234 |
+
--max_model_len MAX_MODEL_LEN, --max-model-len MAX_MODEL_LEN
|
| 235 |
+
If set, the `max_model_len` to use for vLLM. This can be useful when running with reduced `vllm_gpu_memory_utilization`, leading to a
|
| 236 |
+
reduced KV cache size. If not set, vLLM will use the model context size, which might be much larger than the KV cache, leading to
|
| 237 |
+
inefficiencies. (default: None)
|
| 238 |
+
--enable_prefix_caching ENABLE_PREFIX_CACHING, --enable-prefix-caching ENABLE_PREFIX_CACHING
|
| 239 |
+
Whether to enable prefix caching in vLLM. If set to `True`, ensure that the model and the hardware support this feature. (default: None)
|
| 240 |
+
--enforce_eager [ENFORCE_EAGER], --enforce-eager [ENFORCE_EAGER]
|
| 241 |
+
Whether to enforce eager execution. If set to `True`, we will disable CUDA graph and always execute the model in eager mode. If `False`
|
| 242 |
+
(default behavior), we will use CUDA graph and eager execution in hybrid. (default: False)
|
| 243 |
+
--kv_cache_dtype KV_CACHE_DTYPE, --kv-cache-dtype KV_CACHE_DTYPE
|
| 244 |
+
Data type to use for KV cache. If set to 'auto', the dtype will default to the model data type. (default: auto)
|
| 245 |
+
--trust_remote_code [TRUST_REMOTE_CODE], --trust-remote-code [TRUST_REMOTE_CODE]
|
| 246 |
+
Whether to trust remote code when loading models. Set to True to allow executing code from model repositories. This is required for some
|
| 247 |
+
custom models but introduces security risks. (default: False)
|
| 248 |
+
--log_level LOG_LEVEL, --log-level LOG_LEVEL
|
| 249 |
+
Log level for uvicorn. Possible choices: 'critical', 'error', 'warning', 'info', 'debug', 'trace'. (default: info)
|
| 250 |
+
--vllm_model_impl VLLM_MODEL_IMPL, --vllm-model-impl VLLM_MODEL_IMPL
|
| 251 |
+
Model implementation to use for vLLM. Must be one of `transformers` or `vllm`. `transformers`: Use the `transformers` backend for model
|
| 252 |
+
implementation. `vllm`: Use the `vllm` library for model implementation. (default: vllm)
|
| 253 |
+
```
|
| 254 |
+
|
| 255 |
+
### 💆🏻♀️ What's the best distributed setup?
|
| 256 |
+
|
| 257 |
+

|
| 258 |
+

|
| 259 |
+
|
| 260 |
+
> [!WARNING]
|
| 261 |
+
> The benchmark plots above were collected with older vLLM versions. Starting with [vLLM PR #30739](https://github.com/vllm-project/vllm/pull/30739) (released in `0.14.0`), offline data parallel scaling for non-MoE (dense) models is no longer supported. To follow the latest recommendations, do not scale DP for non-MoE models.
|
| 262 |
+
|
| 263 |
+
### vLLM with Transformers Backend
|
| 264 |
+
|
| 265 |
+
vLLM can use the **Transformers backend** for model implementations, which works for both LLMs and VLMs.
|
| 266 |
+
To enable this, set `vllm_model_impl="transformers"` in your configuration or pass it via the command-line argument.
|
| 267 |
+
|
| 268 |
+
For more details, check out [vLLM Transformers Backend](https://blog.vllm.ai/2025/04/11/transformers-backend.html).
|
| 269 |
+
|
| 270 |
+
Example:
|
| 271 |
+
|
| 272 |
+
```sh
|
| 273 |
+
CUDA_DEVICE_ORDER=PCI_BUS_ID CUDA_VISIBLE_DEVICES=0 trl vllm-serve --model Qwen/Qwen
|
| 274 |
+
2.5-VL-3B-Instruct --tensor-parallel-size 1 --port 8000 --enforce_eager --vllm_model_impl transformers
|
| 275 |
+
```
|
| 276 |
+
|
| 277 |
+
### Modes of Using vLLM During Training
|
| 278 |
+
|
| 279 |
+
TRL supports **two modes** for integrating vLLM during training: **colocate mode** (default) and **server mode**.
|
| 280 |
+
|
| 281 |
+
#### Colocate Mode
|
| 282 |
+
|
| 283 |
+
In **colocate mode**, vLLM runs inside the trainer process and shares GPU memory with the training model.
|
| 284 |
+
This avoids launching a separate server and can improve GPU utilization, but may lead to memory contention on the training GPUs. This is the default mode.
|
| 285 |
+
|
| 286 |
+
Example configuration:
|
| 287 |
+
|
| 288 |
+
<hfoptions id="vllm examples">
|
| 289 |
+
<hfoption id="GRPO">
|
| 290 |
+
|
| 291 |
+
```python
|
| 292 |
+
from trl import GRPOConfig
|
| 293 |
+
|
| 294 |
+
training_args = GRPOConfig(
|
| 295 |
+
...,
|
| 296 |
+
use_vllm=True, # vllm_mode="colocate" by default
|
| 297 |
+
)
|
| 298 |
+
```
|
| 299 |
+
|
| 300 |
+
</hfoption>
|
| 301 |
+
<hfoption id="OnlineDPO">
|
| 302 |
+
|
| 303 |
+
```python
|
| 304 |
+
from trl.experimental.online_dpo import OnlineDPOConfig
|
| 305 |
+
|
| 306 |
+
training_args = OnlineDPOConfig(
|
| 307 |
+
...,
|
| 308 |
+
use_vllm=True, # vllm_mode="colocate" by default
|
| 309 |
+
)
|
| 310 |
+
```
|
| 311 |
+
|
| 312 |
+
</hfoption>
|
| 313 |
+
<hfoption id="NashMD">
|
| 314 |
+
|
| 315 |
+
```python
|
| 316 |
+
from trl.experimental.nash_md import NashMDConfig
|
| 317 |
+
|
| 318 |
+
training_args = NashMDConfig(
|
| 319 |
+
...,
|
| 320 |
+
use_vllm=True, # vllm_mode="colocate" by default
|
| 321 |
+
)
|
| 322 |
+
```
|
| 323 |
+
|
| 324 |
+
</hfoption>
|
| 325 |
+
<hfoption id="XPO">
|
| 326 |
+
|
| 327 |
+
```python
|
| 328 |
+
from trl.experimental.xpo import XPOConfig
|
| 329 |
+
|
| 330 |
+
training_args = XPOConfig(
|
| 331 |
+
...,
|
| 332 |
+
use_vllm=True, # vllm_mode="colocate" by default
|
| 333 |
+
)
|
| 334 |
+
```
|
| 335 |
+
|
| 336 |
+
</hfoption>
|
| 337 |
+
<hfoption id="RLOO">
|
| 338 |
+
|
| 339 |
+
```python
|
| 340 |
+
from trl import RLOOConfig
|
| 341 |
+
|
| 342 |
+
training_args = RLOOConfig(
|
| 343 |
+
...,
|
| 344 |
+
use_vllm=True, # vllm_mode="colocate" by default
|
| 345 |
+
)
|
| 346 |
+
```
|
| 347 |
+
|
| 348 |
+
</hfoption>
|
| 349 |
+
</hfoptions>
|
| 350 |
+
|
| 351 |
+
#### Server Mode
|
| 352 |
+
|
| 353 |
+
In **server mode**, vLLM runs as a separate process on dedicated GPUs and communicates with the trainer via HTTP.
|
| 354 |
+
This setup is ideal if you have GPUs dedicated to inference.
|
| 355 |
+
|
| 356 |
+
Example configuration:
|
| 357 |
+
|
| 358 |
+
<hfoptions id="vllm examples">
|
| 359 |
+
<hfoption id="GRPO">
|
| 360 |
+
|
| 361 |
+
```python
|
| 362 |
+
from trl import GRPOConfig
|
| 363 |
+
|
| 364 |
+
training_args = GRPOConfig(
|
| 365 |
+
...,
|
| 366 |
+
use_vllm=True,
|
| 367 |
+
vllm_mode="server",
|
| 368 |
+
)
|
| 369 |
+
```
|
| 370 |
+
|
| 371 |
+
</hfoption>
|
| 372 |
+
<hfoption id="OnlineDPO">
|
| 373 |
+
|
| 374 |
+
```python
|
| 375 |
+
from trl.experimental.online_dpo import OnlineDPOConfig
|
| 376 |
+
|
| 377 |
+
training_args = OnlineDPOConfig(
|
| 378 |
+
...,
|
| 379 |
+
use_vllm=True,
|
| 380 |
+
vllm_mode="server",
|
| 381 |
+
)
|
| 382 |
+
```
|
| 383 |
+
|
| 384 |
+
</hfoption>
|
| 385 |
+
<hfoption id="NashMD">
|
| 386 |
+
|
| 387 |
+
```python
|
| 388 |
+
from trl.experimental.nash_md import NashMDConfig
|
| 389 |
+
|
| 390 |
+
training_args = NashMDConfig(
|
| 391 |
+
...,
|
| 392 |
+
use_vllm=True,
|
| 393 |
+
vllm_mode="server",
|
| 394 |
+
)
|
| 395 |
+
```
|
| 396 |
+
|
| 397 |
+
</hfoption>
|
| 398 |
+
<hfoption id="XPO">
|
| 399 |
+
|
| 400 |
+
```python
|
| 401 |
+
from trl.experimental.xpo import XPOConfig
|
| 402 |
+
|
| 403 |
+
training_args = XPOConfig(
|
| 404 |
+
...,
|
| 405 |
+
use_vllm=True,
|
| 406 |
+
vllm_mode="server",
|
| 407 |
+
)
|
| 408 |
+
```
|
| 409 |
+
|
| 410 |
+
</hfoption>
|
| 411 |
+
<hfoption id="RLOO">
|
| 412 |
+
|
| 413 |
+
```python
|
| 414 |
+
from trl import RLOOConfig
|
| 415 |
+
|
| 416 |
+
training_args = RLOOConfig(
|
| 417 |
+
...,
|
| 418 |
+
use_vllm=True,
|
| 419 |
+
vllm_mode="server",
|
| 420 |
+
)
|
| 421 |
+
```
|
| 422 |
+
|
| 423 |
+
</hfoption>
|
| 424 |
+
</hfoptions>
|
| 425 |
+
|
| 426 |
+
> [!WARNING]
|
| 427 |
+
> Check the documentation of the trainer you are using for specific details on vLLM usage and parameters.
|
| 428 |
+
|
| 429 |
+
> [!WARNING]
|
| 430 |
+
> To reduce GPU memory usage when running vLLM, consider [enabling vLLM sleep mode](reducing_memory_usage#vllm-sleep-mode).
|
tasks/tasksmith-1c108f674e97/tests/source/docs/source/xpo_trainer.md
ADDED
|
@@ -0,0 +1,145 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# XPO Trainer
|
| 2 |
+
|
| 3 |
+
[](https://huggingface.co/models?other=xpo,trl)
|
| 4 |
+
|
| 5 |
+
## Overview
|
| 6 |
+
|
| 7 |
+
Exploratory Preference Optimization (XPO) was proposed in the paper [Exploratory Preference Optimization: Harnessing Implicit Q*-Approximation for Sample-Efficient RLHF](https://huggingface.co/papers/2405.21046) by Tengyang Xie, Dylan J. Foster, Akshay Krishnamurthy, [Corby Rosset](https://huggingface.co/corbyrosset), [Ahmed Awadallah](https://huggingface.co/AhmedAwadallah), and Alexander Rakhlin. It is a simple online preference tuning method based on the DPO loss together with a reward model (RM). XPO augments the DPO objective with an exploration bonus allowing the method to explore outside the support of the initial model and human feedback data.
|
| 8 |
+
|
| 9 |
+
The abstract from the paper is the following:
|
| 10 |
+
|
| 11 |
+
> Reinforcement learning from human feedback (RLHF) has emerged as a central tool for language model alignment. We consider online exploration in RLHF, which exploits interactive access to human or AI feedback by deliberately encouraging the model to produce diverse, maximally informative responses. By allowing RLHF to confidently stray from the pre-trained model, online exploration offers the possibility of novel, potentially super-human capabilities, but its full potential as a paradigm for language model training has yet to be realized, owing to computational and statistical bottlenecks in directly adapting existing reinforcement learning techniques. We propose a new algorithm for online exploration in RLHF, Exploratory Preference Optimization (XPO), which is simple and practical -- a one-line change to (online) Direct Preference Optimization (DPO; Rafailov et al., 2023) -- yet enjoys the strongest known provable guarantees and promising empirical performance. XPO augments the DPO objective with a novel and principled exploration bonus, empowering the algorithm to explore outside the support of the initial model and human feedback data. In theory, we show that XPO is provably sample-efficient and converges to a near-optimal language model policy under natural exploration conditions, irrespective of whether the initial model has good coverage. Our analysis, which builds on the observation that DPO implicitly performs a form of Q*-approximation (or, Bellman error minimization), combines previously disparate techniques from language modeling and theoretical reinforcement learning in a serendipitous fashion through the perspective of KL-regularized Markov decision processes. Empirically, we find that XPO is more sample-efficient than non-exploratory DPO variants in a preliminary evaluation.
|
| 12 |
+
|
| 13 |
+
This post-training method was contributed by [Kashif Rasul](https://huggingface.co/kashif), [Quentin Gallouédec](https://huggingface.co/qgallouedec) and [Lewis Tunstall](https://huggingface.co/lewtun).
|
| 14 |
+
|
| 15 |
+
> [!NOTE]
|
| 16 |
+
> XPO is currently experimental. The API may change without notice while the feature is iterated on.
|
| 17 |
+
|
| 18 |
+
## Quick start
|
| 19 |
+
|
| 20 |
+
This example demonstrates how to train a model using the XPO method. We use the [Qwen 0.5B model](https://huggingface.co/Qwen/Qwen2-0.5B-Instruct) as the base model and the [trl-lib/Qwen2-0.5B-Reward](https://huggingface.co/trl-lib/Qwen2-0.5B-Reward) reward model. We use the prompts from the [UltraFeedback dataset](https://huggingface.co/datasets/openbmb/UltraFeedback). You can view the prompts in the dataset here:
|
| 21 |
+
<iframe
|
| 22 |
+
src="https://huggingface.co/datasets/trl-lib/ultrafeedback-prompt/embed/viewer/default/train?row=0"
|
| 23 |
+
frameborder="0"
|
| 24 |
+
width="100%"
|
| 25 |
+
height="560px"
|
| 26 |
+
></iframe>
|
| 27 |
+
|
| 28 |
+
Below is the script to train the model:
|
| 29 |
+
|
| 30 |
+
```python
|
| 31 |
+
# train_xpo.py
|
| 32 |
+
from datasets import load_dataset
|
| 33 |
+
from trl.experimental.xpo import XPOConfig, XPOTrainer
|
| 34 |
+
from transformers import AutoModelForCausalLM, AutoModelForSequenceClassification, AutoTokenizer
|
| 35 |
+
|
| 36 |
+
model = AutoModelForCausalLM.from_pretrained("Qwen/Qwen2-0.5B-Instruct")
|
| 37 |
+
tokenizer = AutoTokenizer.from_pretrained("Qwen/Qwen2-0.5B-Instruct")
|
| 38 |
+
reward_model = AutoModelForSequenceClassification.from_pretrained("trl-lib/Qwen2-0.5B-Reward", num_labels=1)
|
| 39 |
+
train_dataset = load_dataset("trl-lib/ultrafeedback-prompt", split="train")
|
| 40 |
+
|
| 41 |
+
training_args = XPOConfig(output_dir="Qwen2-0.5B-XPO")
|
| 42 |
+
trainer = XPOTrainer(
|
| 43 |
+
model=model, reward_funcs=reward_model, args=training_args, processing_class=tokenizer, train_dataset=train_dataset
|
| 44 |
+
)
|
| 45 |
+
trainer.train()
|
| 46 |
+
```
|
| 47 |
+
|
| 48 |
+
Execute the script using the following command:
|
| 49 |
+
|
| 50 |
+
```bash
|
| 51 |
+
accelerate launch train_xpo.py
|
| 52 |
+
```
|
| 53 |
+
|
| 54 |
+
Distributed across 8 GPUs, the training takes approximately 1 hour.
|
| 55 |
+
|
| 56 |
+
To see how the [trained model](https://huggingface.co/trl-lib/Qwen2-0.5B-XPO) performs, you can use the [Transformers Chat CLI](https://huggingface.co/docs/transformers/quicktour#chat-with-text-generation-models).
|
| 57 |
+
|
| 58 |
+
<pre><code>$ transformers chat trl-lib/Qwen2-0.5B-XPO
|
| 59 |
+
<strong><span style="color: red;"><quentin_gallouedec>:</span></strong>
|
| 60 |
+
What is the best programming language?
|
| 61 |
+
|
| 62 |
+
<strong><span style="color: blue;"><trl-lib/Qwen2-0.5B-XPO>:</span></strong>
|
| 63 |
+
The best programming language depends on individual preferences and familiarity with coding concepts. Some popular languages include Python, Java, C++, and JavaScript.
|
| 64 |
+
</code></pre>
|
| 65 |
+
|
| 66 |
+
## Expected dataset type
|
| 67 |
+
|
| 68 |
+
XPO requires a [prompt-only dataset](dataset_formats#prompt-only). The [`experimental.xpo.XPOTrainer`] supports both [conversational](dataset_formats#conversational) and [standard](dataset_formats#standard) dataset format. When provided with a conversational dataset, the trainer will automatically apply the chat template to the dataset.
|
| 69 |
+
|
| 70 |
+
## Usage tips
|
| 71 |
+
|
| 72 |
+
### Encourage EOS token generation
|
| 73 |
+
|
| 74 |
+
When using a reward model, we may want the model to generate completions within a given length. During training, the model will generate completions up to the maximum length specified in the `max_new_tokens` argument of [`experimental.xpo.XPOConfig`]. If you want to penalize the model for not generating an EOS token before reaching the maximum length, you can use the `missing_eos_penalty` argument of [`experimental.xpo.XPOConfig`]:
|
| 75 |
+
|
| 76 |
+
```python
|
| 77 |
+
training_args = XPOConfig(..., max_new_tokens=128, missing_eos_penalty=1.0)
|
| 78 |
+
```
|
| 79 |
+
|
| 80 |
+
> [!WARNING]
|
| 81 |
+
> Make sure that the SFT model and reward model use the _same_ chat template and the same tokenizer. Otherwise, you may find the model completions are scored incorrectly during training.
|
| 82 |
+
|
| 83 |
+
### Logging Completions
|
| 84 |
+
|
| 85 |
+
To better understand your model's behavior during training, you can log sample completions periodically using the [`LogCompletionsCallback`].
|
| 86 |
+
|
| 87 |
+
```python
|
| 88 |
+
trainer = XPOTrainer(..., eval_dataset=eval_dataset)
|
| 89 |
+
completions_callback = LogCompletionsCallback(trainer, num_prompts=8)
|
| 90 |
+
trainer.add_callback(completions_callback)
|
| 91 |
+
```
|
| 92 |
+
|
| 93 |
+
This callback logs the model's generated completions directly to Weights & Biases.
|
| 94 |
+
|
| 95 |
+

|
| 96 |
+
|
| 97 |
+
## Example script
|
| 98 |
+
|
| 99 |
+
We provide an example script to train a model using the XPO method. The script is available in [`examples/scripts/xpo.py`](https://github.com/huggingface/trl/blob/main/examples/scripts/xpo.py)
|
| 100 |
+
|
| 101 |
+
To test the XPO script with the [Qwen2.5 0.5B model](https://huggingface.co/trl-lib/Qwen/Qwen2.5-0.5B-Instruct) on the [UltraFeedback dataset](https://huggingface.co/datasets/openbmb/UltraFeedback), run the following command:
|
| 102 |
+
|
| 103 |
+
```bash
|
| 104 |
+
python examples/scripts/xpo.py \
|
| 105 |
+
--model_name_or_path Qwen/Qwen2.5-0.5B-Instruct \
|
| 106 |
+
--reward_model_path trl-lib/Qwen2-0.5B-Reward \
|
| 107 |
+
--dataset_name trl-lib/ultrafeedback-prompt \
|
| 108 |
+
--learning_rate 5.0e-7 \
|
| 109 |
+
--output_dir Qwen2.5-0.5B-XPO \
|
| 110 |
+
--warmup_steps 0.1 \
|
| 111 |
+
--push_to_hub
|
| 112 |
+
```
|
| 113 |
+
|
| 114 |
+
## Logged metrics
|
| 115 |
+
|
| 116 |
+
While training and evaluating we record the following reward metrics:
|
| 117 |
+
|
| 118 |
+
* `loss/xpo`: The mean xpo part of the full loss.
|
| 119 |
+
* `loss/dpo`: The mean dpo part of the full loss.
|
| 120 |
+
* `objective/kl`: The mean KL divergence between the model and reference data.
|
| 121 |
+
* `objective/entropy`: The mean entropy of the model and reference data.
|
| 122 |
+
* `objective/model_scores`: The mean scores (according to the reward model) of the model completions.
|
| 123 |
+
* `objective/ref_scores`: The mean scores (according to the reward model) of the reference completions.
|
| 124 |
+
* `objective/scores_margin`: The mean score margin (according to the external reward model) between the chosen and rejected completions.
|
| 125 |
+
* `rewards/chosen`: The mean reward (according to XPO's DPO implicit reward model) of the chosen completions.
|
| 126 |
+
* `rewards/rejected`: The mean reward (according to XPO's DPO implicit reward model) of the rejected completions.
|
| 127 |
+
* `rewards/accuracies`: The accuracies of the XPO's implicit reward model.
|
| 128 |
+
* `rewards/margins`: The mean reward margin (according to online DPO's implicit reward model) between the chosen and rejected completions.
|
| 129 |
+
* `logps/chosen`: The mean log probabilities of the chosen completions.
|
| 130 |
+
* `logps/rejected`: The mean log probabilities of the rejected completions.
|
| 131 |
+
* `val/model_contain_eos_token`: The amount of times the model's output contains the eos token.
|
| 132 |
+
* `val/ref_contain_eos_token`: The amount of times the reference's output contains the eos token.
|
| 133 |
+
* `alpha`: The weight of the XPO loss term. Typically fixed, but can be made dynamic by passing a list to [`experimental.xpo.XPOConfig`].
|
| 134 |
+
* `beta`: The parameter that controls the weight of the loss term representing the deviation from the reference model. Typically fixed, but can be made dynamic by passing a list to [`experimental.xpo.XPOConfig`].
|
| 135 |
+
|
| 136 |
+
## XPOTrainer
|
| 137 |
+
|
| 138 |
+
[[autodoc]] experimental.xpo.XPOTrainer
|
| 139 |
+
- train
|
| 140 |
+
- save_model
|
| 141 |
+
- push_to_hub
|
| 142 |
+
|
| 143 |
+
## XPOConfig
|
| 144 |
+
|
| 145 |
+
[[autodoc]] experimental.xpo.XPOConfig
|
tasks/tasksmith-1c108f674e97/tests/source/examples/README.md
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Examples
|
| 2 |
+
|
| 3 |
+
Please check out https://huggingface.co/docs/trl/example_overview for documentation on our examples.
|
tasks/tasksmith-1c108f674e97/tests/source/examples/accelerate_configs/alst_ulysses_4gpu.yaml
ADDED
|
@@ -0,0 +1,45 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# ALST/Ulysses Sequence Parallelism with 2D Parallelism (DP + SP) for 4 GPUs
|
| 2 |
+
#
|
| 3 |
+
# This configuration enables 2D parallelism:
|
| 4 |
+
# - Sequence Parallelism (sp_size=2): Sequences split across 2 GPUs using ALST/Ulysses
|
| 5 |
+
# - Data Parallelism (dp_shard_size=2): Model/optimizer sharded across 2 GPUs
|
| 6 |
+
# - Total: 4 GPUs (2 × 2)
|
| 7 |
+
#
|
| 8 |
+
# Set parallelism_config in your training script:
|
| 9 |
+
# parallelism_config = ParallelismConfig(
|
| 10 |
+
# sp_backend="deepspeed",
|
| 11 |
+
# sp_size=2,
|
| 12 |
+
# dp_shard_size=2, # Calculated as: num_gpus // sp_size
|
| 13 |
+
# sp_handler=DeepSpeedSequenceParallelConfig(...)
|
| 14 |
+
# )
|
| 15 |
+
|
| 16 |
+
compute_environment: LOCAL_MACHINE
|
| 17 |
+
debug: false
|
| 18 |
+
deepspeed_config:
|
| 19 |
+
zero_stage: 3
|
| 20 |
+
seq_parallel_communication_data_type: bf16
|
| 21 |
+
offload_optimizer_device: none
|
| 22 |
+
offload_param_device: none
|
| 23 |
+
zero3_init_flag: true
|
| 24 |
+
zero3_save_16bit_model: true
|
| 25 |
+
distributed_type: DEEPSPEED
|
| 26 |
+
downcast_bf16: 'no'
|
| 27 |
+
machine_rank: 0
|
| 28 |
+
main_training_function: main
|
| 29 |
+
mixed_precision: bf16
|
| 30 |
+
num_machines: 1
|
| 31 |
+
num_processes: 4 # Total number of GPUs
|
| 32 |
+
rdzv_backend: static
|
| 33 |
+
same_network: true
|
| 34 |
+
tpu_env: []
|
| 35 |
+
tpu_use_cluster: false
|
| 36 |
+
tpu_use_sudo: false
|
| 37 |
+
use_cpu: false
|
| 38 |
+
parallelism_config:
|
| 39 |
+
parallelism_config_dp_replicate_size: 1
|
| 40 |
+
parallelism_config_dp_shard_size: 2 # Enables 2D parallelism with SP
|
| 41 |
+
parallelism_config_tp_size: 1
|
| 42 |
+
parallelism_config_sp_size: 2 # Sequence parallel size
|
| 43 |
+
parallelism_config_sp_backend: deepspeed
|
| 44 |
+
parallelism_config_sp_seq_length_is_variable: true
|
| 45 |
+
parallelism_config_sp_attn_implementation: flash_attention_2
|
tasks/tasksmith-1c108f674e97/tests/source/examples/accelerate_configs/context_parallel_2gpu.yaml
ADDED
|
@@ -0,0 +1,30 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Context Parallelism with FSDP for 2 GPUs
|
| 2 |
+
compute_environment: LOCAL_MACHINE
|
| 3 |
+
debug: false
|
| 4 |
+
distributed_type: FSDP
|
| 5 |
+
downcast_bf16: 'no'
|
| 6 |
+
enable_cpu_affinity: false
|
| 7 |
+
fsdp_config:
|
| 8 |
+
fsdp_activation_checkpointing: true # Enable activation checkpointing for memory efficiency
|
| 9 |
+
fsdp_auto_wrap_policy: TRANSFORMER_BASED_WRAP
|
| 10 |
+
fsdp_cpu_ram_efficient_loading: true
|
| 11 |
+
fsdp_offload_params: false
|
| 12 |
+
fsdp_reshard_after_forward: true
|
| 13 |
+
fsdp_state_dict_type: FULL_STATE_DICT
|
| 14 |
+
fsdp_version: 2
|
| 15 |
+
machine_rank: 0
|
| 16 |
+
main_training_function: main
|
| 17 |
+
mixed_precision: bf16
|
| 18 |
+
num_machines: 1
|
| 19 |
+
num_processes: 2 # Number of GPUs
|
| 20 |
+
rdzv_backend: static
|
| 21 |
+
same_network: true
|
| 22 |
+
tpu_env: []
|
| 23 |
+
tpu_use_cluster: false
|
| 24 |
+
tpu_use_sudo: false
|
| 25 |
+
use_cpu: false
|
| 26 |
+
parallelism_config:
|
| 27 |
+
parallelism_config_dp_replicate_size: 1
|
| 28 |
+
parallelism_config_dp_shard_size: 1
|
| 29 |
+
parallelism_config_tp_size: 1
|
| 30 |
+
parallelism_config_cp_size: 2 # Context parallel size
|
tasks/tasksmith-1c108f674e97/tests/source/examples/accelerate_configs/deepspeed_zero1.yaml
ADDED
|
@@ -0,0 +1,20 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
compute_environment: LOCAL_MACHINE
|
| 2 |
+
debug: false
|
| 3 |
+
deepspeed_config:
|
| 4 |
+
deepspeed_multinode_launcher: standard
|
| 5 |
+
gradient_accumulation_steps: 1
|
| 6 |
+
zero3_init_flag: false
|
| 7 |
+
zero_stage: 1
|
| 8 |
+
distributed_type: DEEPSPEED
|
| 9 |
+
downcast_bf16: 'no'
|
| 10 |
+
machine_rank: 0
|
| 11 |
+
main_training_function: main
|
| 12 |
+
mixed_precision: 'bf16'
|
| 13 |
+
num_machines: 1
|
| 14 |
+
num_processes: 8
|
| 15 |
+
rdzv_backend: static
|
| 16 |
+
same_network: true
|
| 17 |
+
tpu_env: []
|
| 18 |
+
tpu_use_cluster: false
|
| 19 |
+
tpu_use_sudo: false
|
| 20 |
+
use_cpu: false
|
tasks/tasksmith-1c108f674e97/tests/source/examples/accelerate_configs/deepspeed_zero2.yaml
ADDED
|
@@ -0,0 +1,21 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
compute_environment: LOCAL_MACHINE
|
| 2 |
+
debug: false
|
| 3 |
+
deepspeed_config:
|
| 4 |
+
deepspeed_multinode_launcher: standard
|
| 5 |
+
offload_optimizer_device: none
|
| 6 |
+
offload_param_device: none
|
| 7 |
+
zero3_init_flag: false
|
| 8 |
+
zero_stage: 2
|
| 9 |
+
distributed_type: DEEPSPEED
|
| 10 |
+
downcast_bf16: 'no'
|
| 11 |
+
machine_rank: 0
|
| 12 |
+
main_training_function: main
|
| 13 |
+
mixed_precision: 'bf16'
|
| 14 |
+
num_machines: 1
|
| 15 |
+
num_processes: 8
|
| 16 |
+
rdzv_backend: static
|
| 17 |
+
same_network: true
|
| 18 |
+
tpu_env: []
|
| 19 |
+
tpu_use_cluster: false
|
| 20 |
+
tpu_use_sudo: false
|
| 21 |
+
use_cpu: false
|
tasks/tasksmith-1c108f674e97/tests/source/examples/accelerate_configs/deepspeed_zero3.yaml
ADDED
|
@@ -0,0 +1,22 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
compute_environment: LOCAL_MACHINE
|
| 2 |
+
debug: false
|
| 3 |
+
deepspeed_config:
|
| 4 |
+
deepspeed_multinode_launcher: standard
|
| 5 |
+
offload_optimizer_device: none
|
| 6 |
+
offload_param_device: none
|
| 7 |
+
zero3_init_flag: true
|
| 8 |
+
zero3_save_16bit_model: true
|
| 9 |
+
zero_stage: 3
|
| 10 |
+
distributed_type: DEEPSPEED
|
| 11 |
+
downcast_bf16: 'no'
|
| 12 |
+
machine_rank: 0
|
| 13 |
+
main_training_function: main
|
| 14 |
+
mixed_precision: bf16
|
| 15 |
+
num_machines: 1
|
| 16 |
+
num_processes: 8
|
| 17 |
+
rdzv_backend: static
|
| 18 |
+
same_network: true
|
| 19 |
+
tpu_env: []
|
| 20 |
+
tpu_use_cluster: false
|
| 21 |
+
tpu_use_sudo: false
|
| 22 |
+
use_cpu: false
|
tasks/tasksmith-1c108f674e97/tests/source/examples/accelerate_configs/fsdp1.yaml
ADDED
|
@@ -0,0 +1,28 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
compute_environment: LOCAL_MACHINE
|
| 2 |
+
debug: false
|
| 3 |
+
distributed_type: FSDP
|
| 4 |
+
downcast_bf16: 'no'
|
| 5 |
+
enable_cpu_affinity: false
|
| 6 |
+
fsdp_config:
|
| 7 |
+
fsdp_activation_checkpointing: false
|
| 8 |
+
fsdp_auto_wrap_policy: TRANSFORMER_BASED_WRAP
|
| 9 |
+
fsdp_backward_prefetch: BACKWARD_PRE
|
| 10 |
+
fsdp_cpu_ram_efficient_loading: true
|
| 11 |
+
fsdp_forward_prefetch: true
|
| 12 |
+
fsdp_offload_params: false
|
| 13 |
+
fsdp_reshard_after_forward: FULL_SHARD
|
| 14 |
+
fsdp_state_dict_type: FULL_STATE_DICT
|
| 15 |
+
fsdp_sync_module_states: true
|
| 16 |
+
fsdp_use_orig_params: true
|
| 17 |
+
fsdp_version: 1
|
| 18 |
+
machine_rank: 0
|
| 19 |
+
main_training_function: main
|
| 20 |
+
mixed_precision: bf16
|
| 21 |
+
num_machines: 1
|
| 22 |
+
num_processes: 8
|
| 23 |
+
rdzv_backend: static
|
| 24 |
+
same_network: true
|
| 25 |
+
tpu_env: []
|
| 26 |
+
tpu_use_cluster: false
|
| 27 |
+
tpu_use_sudo: false
|
| 28 |
+
use_cpu: false
|
tasks/tasksmith-1c108f674e97/tests/source/examples/accelerate_configs/fsdp2.yaml
ADDED
|
@@ -0,0 +1,25 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Requires accelerate 1.7.0 or higher
|
| 2 |
+
compute_environment: LOCAL_MACHINE
|
| 3 |
+
debug: false
|
| 4 |
+
distributed_type: FSDP
|
| 5 |
+
downcast_bf16: 'no'
|
| 6 |
+
enable_cpu_affinity: false
|
| 7 |
+
fsdp_config:
|
| 8 |
+
fsdp_activation_checkpointing: false
|
| 9 |
+
fsdp_auto_wrap_policy: TRANSFORMER_BASED_WRAP
|
| 10 |
+
fsdp_cpu_ram_efficient_loading: true
|
| 11 |
+
fsdp_offload_params: false
|
| 12 |
+
fsdp_reshard_after_forward: true
|
| 13 |
+
fsdp_state_dict_type: FULL_STATE_DICT
|
| 14 |
+
fsdp_version: 2
|
| 15 |
+
machine_rank: 0
|
| 16 |
+
main_training_function: main
|
| 17 |
+
mixed_precision: bf16
|
| 18 |
+
num_machines: 1
|
| 19 |
+
num_processes: 8
|
| 20 |
+
rdzv_backend: static
|
| 21 |
+
same_network: true
|
| 22 |
+
tpu_env: []
|
| 23 |
+
tpu_use_cluster: false
|
| 24 |
+
tpu_use_sudo: false
|
| 25 |
+
use_cpu: false
|
tasks/tasksmith-1c108f674e97/tests/source/examples/accelerate_configs/multi_gpu.yaml
ADDED
|
@@ -0,0 +1,16 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
compute_environment: LOCAL_MACHINE
|
| 2 |
+
debug: false
|
| 3 |
+
distributed_type: MULTI_GPU
|
| 4 |
+
downcast_bf16: 'no'
|
| 5 |
+
gpu_ids: all
|
| 6 |
+
machine_rank: 0
|
| 7 |
+
main_training_function: main
|
| 8 |
+
mixed_precision: 'bf16'
|
| 9 |
+
num_machines: 1
|
| 10 |
+
num_processes: 8
|
| 11 |
+
rdzv_backend: static
|
| 12 |
+
same_network: true
|
| 13 |
+
tpu_env: []
|
| 14 |
+
tpu_use_cluster: false
|
| 15 |
+
tpu_use_sudo: false
|
| 16 |
+
use_cpu: false
|
tasks/tasksmith-1c108f674e97/tests/source/examples/accelerate_configs/single_gpu.yaml
ADDED
|
@@ -0,0 +1,16 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
compute_environment: LOCAL_MACHINE
|
| 2 |
+
debug: false
|
| 3 |
+
distributed_type: "NO"
|
| 4 |
+
downcast_bf16: 'no'
|
| 5 |
+
gpu_ids: all
|
| 6 |
+
machine_rank: 0
|
| 7 |
+
main_training_function: main
|
| 8 |
+
mixed_precision: 'bf16'
|
| 9 |
+
num_machines: 1
|
| 10 |
+
num_processes: 1
|
| 11 |
+
rdzv_backend: static
|
| 12 |
+
same_network: true
|
| 13 |
+
tpu_env: []
|
| 14 |
+
tpu_use_cluster: false
|
| 15 |
+
tpu_use_sudo: false
|
| 16 |
+
use_cpu: false
|
tasks/tasksmith-1c108f674e97/tests/source/examples/cli_configs/example_config.yaml
ADDED
|
@@ -0,0 +1,18 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# This is an example configuration file of TRL CLI, you can use it for
|
| 2 |
+
# SFT like that: `trl sft --config config.yaml --output_dir test-sft`
|
| 3 |
+
# The YAML file supports environment variables by adding an `env` field
|
| 4 |
+
# as below
|
| 5 |
+
|
| 6 |
+
# env:
|
| 7 |
+
# CUDA_VISIBLE_DEVICES: 0
|
| 8 |
+
|
| 9 |
+
model_name_or_path:
|
| 10 |
+
Qwen/Qwen2.5-0.5B
|
| 11 |
+
dataset_name:
|
| 12 |
+
stanfordnlp/imdb
|
| 13 |
+
report_to:
|
| 14 |
+
none
|
| 15 |
+
learning_rate:
|
| 16 |
+
0.0001
|
| 17 |
+
lr_scheduler_type:
|
| 18 |
+
cosine
|
tasks/tasksmith-1c108f674e97/tests/source/examples/datasets/deepmath_103k.py
ADDED
|
@@ -0,0 +1,98 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Copyright 2020-2026 The HuggingFace Team. All rights reserved.
|
| 2 |
+
#
|
| 3 |
+
# Licensed under the Apache License, Version 2.0 (the "License");
|
| 4 |
+
# you may not use this file except in compliance with the License.
|
| 5 |
+
# You may obtain a copy of the License at
|
| 6 |
+
#
|
| 7 |
+
# http://www.apache.org/licenses/LICENSE-2.0
|
| 8 |
+
#
|
| 9 |
+
# Unless required by applicable law or agreed to in writing, software
|
| 10 |
+
# distributed under the License is distributed on an "AS IS" BASIS,
|
| 11 |
+
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
| 12 |
+
# See the License for the specific language governing permissions and
|
| 13 |
+
# limitations under the License.
|
| 14 |
+
|
| 15 |
+
from dataclasses import dataclass, field
|
| 16 |
+
|
| 17 |
+
from datasets import load_dataset
|
| 18 |
+
from huggingface_hub import ModelCard
|
| 19 |
+
from transformers import HfArgumentParser
|
| 20 |
+
|
| 21 |
+
|
| 22 |
+
@dataclass
|
| 23 |
+
class ScriptArguments:
|
| 24 |
+
r"""
|
| 25 |
+
Arguments for the script.
|
| 26 |
+
|
| 27 |
+
Args:
|
| 28 |
+
push_to_hub (`bool`, *optional*, defaults to `False`):
|
| 29 |
+
Whether to push the dataset to the Hugging Face Hub.
|
| 30 |
+
repo_id (`str`, *optional*, defaults to `"trl-lib/DeepMath-103K"`):
|
| 31 |
+
Hugging Face repository ID to push the dataset to.
|
| 32 |
+
dataset_num_proc (`int`, *optional*):
|
| 33 |
+
Number of workers to use for dataset processing.
|
| 34 |
+
"""
|
| 35 |
+
|
| 36 |
+
push_to_hub: bool = field(
|
| 37 |
+
default=False,
|
| 38 |
+
metadata={"help": "Whether to push the dataset to the Hugging Face Hub."},
|
| 39 |
+
)
|
| 40 |
+
repo_id: str = field(
|
| 41 |
+
default="trl-lib/DeepMath-103K",
|
| 42 |
+
metadata={"help": "Hugging Face repository ID to push the dataset to."},
|
| 43 |
+
)
|
| 44 |
+
dataset_num_proc: int | None = field(
|
| 45 |
+
default=None,
|
| 46 |
+
metadata={"help": "Number of workers to use for dataset processing."},
|
| 47 |
+
)
|
| 48 |
+
|
| 49 |
+
|
| 50 |
+
def process_example(example):
|
| 51 |
+
solution = example["final_answer"]
|
| 52 |
+
if solution not in ["True", "False", "Yes", "No"]:
|
| 53 |
+
solution = f"${solution}$"
|
| 54 |
+
prompt = [{"role": "user", "content": example["question"]}]
|
| 55 |
+
return {"prompt": prompt, "solution": solution}
|
| 56 |
+
|
| 57 |
+
|
| 58 |
+
model_card = ModelCard("""
|
| 59 |
+
---
|
| 60 |
+
tags: [trl]
|
| 61 |
+
---
|
| 62 |
+
|
| 63 |
+
# DeepMath-103K Dataset
|
| 64 |
+
|
| 65 |
+
## Summary
|
| 66 |
+
|
| 67 |
+
[DeepMath-103K](https://huggingface.co/datasets/zwhe99/DeepMath-103K) is meticulously curated to push the boundaries of mathematical reasoning in language models.
|
| 68 |
+
|
| 69 |
+
## Data Structure
|
| 70 |
+
|
| 71 |
+
- **Format**: [Conversational](https://huggingface.co/docs/trl/main/dataset_formats#conversational)
|
| 72 |
+
- **Type**: [Prompt-only](https://huggingface.co/docs/trl/main/dataset_formats#prompt-only)
|
| 73 |
+
|
| 74 |
+
Column:
|
| 75 |
+
- `"prompt"`: The input question.
|
| 76 |
+
- `"solution"`: The solution to the math problem.
|
| 77 |
+
|
| 78 |
+
## Generation script
|
| 79 |
+
|
| 80 |
+
The script used to generate this dataset can be found [here](https://github.com/huggingface/trl/blob/main/examples/datasets/deepmath_103k.py).
|
| 81 |
+
""")
|
| 82 |
+
|
| 83 |
+
if __name__ == "__main__":
|
| 84 |
+
parser = HfArgumentParser(ScriptArguments)
|
| 85 |
+
script_args = parser.parse_args_into_dataclasses()[0]
|
| 86 |
+
|
| 87 |
+
dataset = load_dataset("zwhe99/DeepMath-103K", split="train")
|
| 88 |
+
|
| 89 |
+
dataset = dataset.map(
|
| 90 |
+
process_example,
|
| 91 |
+
remove_columns=dataset.column_names,
|
| 92 |
+
num_proc=script_args.dataset_num_proc,
|
| 93 |
+
)
|
| 94 |
+
dataset = dataset.train_test_split(test_size=0.05, seed=42)
|
| 95 |
+
|
| 96 |
+
if script_args.push_to_hub:
|
| 97 |
+
dataset.push_to_hub(script_args.repo_id)
|
| 98 |
+
model_card.push_to_hub(script_args.repo_id, repo_type="dataset")
|
tasks/tasksmith-1c108f674e97/tests/source/examples/datasets/hh-rlhf-helpful-base.py
ADDED
|
@@ -0,0 +1,132 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Copyright 2020-2026 The HuggingFace Team. All rights reserved.
|
| 2 |
+
#
|
| 3 |
+
# Licensed under the Apache License, Version 2.0 (the "License");
|
| 4 |
+
# you may not use this file except in compliance with the License.
|
| 5 |
+
# You may obtain a copy of the License at
|
| 6 |
+
#
|
| 7 |
+
# http://www.apache.org/licenses/LICENSE-2.0
|
| 8 |
+
#
|
| 9 |
+
# Unless required by applicable law or agreed to in writing, software
|
| 10 |
+
# distributed under the License is distributed on an "AS IS" BASIS,
|
| 11 |
+
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
| 12 |
+
# See the License for the specific language governing permissions and
|
| 13 |
+
# limitations under the License.
|
| 14 |
+
|
| 15 |
+
import re
|
| 16 |
+
from dataclasses import dataclass, field
|
| 17 |
+
|
| 18 |
+
from datasets import load_dataset
|
| 19 |
+
from huggingface_hub import ModelCard
|
| 20 |
+
from transformers import HfArgumentParser
|
| 21 |
+
|
| 22 |
+
|
| 23 |
+
@dataclass
|
| 24 |
+
class ScriptArguments:
|
| 25 |
+
r"""
|
| 26 |
+
Arguments for the script.
|
| 27 |
+
|
| 28 |
+
Args:
|
| 29 |
+
push_to_hub (`bool`, *optional*, defaults to `False`):
|
| 30 |
+
Whether to push the dataset to the Hugging Face Hub.
|
| 31 |
+
repo_id (`str`, *optional*, defaults to `"trl-lib/hh-rlhf-helpful-base"`):
|
| 32 |
+
Hugging Face repository ID to push the dataset to.
|
| 33 |
+
dataset_num_proc (`int`, *optional*):
|
| 34 |
+
Number of workers to use for dataset processing.
|
| 35 |
+
"""
|
| 36 |
+
|
| 37 |
+
push_to_hub: bool = field(
|
| 38 |
+
default=False,
|
| 39 |
+
metadata={"help": "Whether to push the dataset to the Hugging Face Hub."},
|
| 40 |
+
)
|
| 41 |
+
repo_id: str = field(
|
| 42 |
+
default="trl-lib/hh-rlhf-helpful-base", metadata={"help": "Hugging Face repository ID to push the dataset to."}
|
| 43 |
+
)
|
| 44 |
+
dataset_num_proc: int | None = field(
|
| 45 |
+
default=None, metadata={"help": "Number of workers to use for dataset processing."}
|
| 46 |
+
)
|
| 47 |
+
|
| 48 |
+
|
| 49 |
+
def common_start(str1: str, str2: str) -> str:
|
| 50 |
+
# Zip the two strings and iterate over them together
|
| 51 |
+
common_chars = []
|
| 52 |
+
for c1, c2 in zip(str1, str2, strict=True):
|
| 53 |
+
if c1 == c2:
|
| 54 |
+
common_chars.append(c1)
|
| 55 |
+
else:
|
| 56 |
+
break
|
| 57 |
+
# Join the common characters and return as a string
|
| 58 |
+
return "".join(common_chars)
|
| 59 |
+
|
| 60 |
+
|
| 61 |
+
def extract_dialogue(example: str) -> list[dict[str, str]]:
|
| 62 |
+
# Extract the prompt, which corresponds to the common start of the chosen and rejected dialogues
|
| 63 |
+
prompt_text = common_start(example["chosen"], example["rejected"])
|
| 64 |
+
|
| 65 |
+
# The chosen and rejected may share a common start, so we need to remove the common part
|
| 66 |
+
if not prompt_text.endswith("\n\nAssistant: "):
|
| 67 |
+
prompt_text = prompt_text[: prompt_text.rfind("\n\nAssistant: ")] + "\n\nAssistant: "
|
| 68 |
+
|
| 69 |
+
# Extract the chosen and rejected lines
|
| 70 |
+
chosen_line = example["chosen"][len(prompt_text) :]
|
| 71 |
+
rejected_line = example["rejected"][len(prompt_text) :]
|
| 72 |
+
|
| 73 |
+
# Remove the generation prompt ("\n\nAssistant: ") from the prompt
|
| 74 |
+
prompt_text = prompt_text[: -len("\n\nAssistant: ")]
|
| 75 |
+
|
| 76 |
+
# Split the string at every occurrence of "Human: " or "Assistant: "
|
| 77 |
+
prompt_lines = re.split(r"(\n\nAssistant: |\n\nHuman: )", prompt_text)
|
| 78 |
+
|
| 79 |
+
# Remove the first element as it's empty
|
| 80 |
+
prompt_lines = prompt_lines[1:]
|
| 81 |
+
|
| 82 |
+
prompt = []
|
| 83 |
+
for idx in range(0, len(prompt_lines), 2):
|
| 84 |
+
role = "user" if prompt_lines[idx] == "\n\nHuman: " else "assistant"
|
| 85 |
+
content = prompt_lines[idx + 1]
|
| 86 |
+
prompt.append({"role": role, "content": content})
|
| 87 |
+
|
| 88 |
+
# Remove the prompt from the chosen and rejected dialogues
|
| 89 |
+
chosen = [{"role": "assistant", "content": chosen_line}]
|
| 90 |
+
rejected = [{"role": "assistant", "content": rejected_line}]
|
| 91 |
+
|
| 92 |
+
return {"prompt": prompt, "chosen": chosen, "rejected": rejected}
|
| 93 |
+
|
| 94 |
+
|
| 95 |
+
model_card = ModelCard("""
|
| 96 |
+
---
|
| 97 |
+
tags: [trl]
|
| 98 |
+
---
|
| 99 |
+
|
| 100 |
+
# HH-RLHF-Helpful-Base Dataset
|
| 101 |
+
|
| 102 |
+
## Summary
|
| 103 |
+
|
| 104 |
+
The HH-RLHF-Helpful-Base dataset is a processed version of [Anthropic's HH-RLHF](https://huggingface.co/datasets/Anthropic/hh-rlhf) dataset, specifically curated to train models using the [TRL library](https://github.com/huggingface/trl) for preference learning and alignment tasks. It contains pairs of text samples, each labeled as either "chosen" or "rejected," based on human preferences regarding the helpfulness of the responses. This dataset enables models to learn human preferences in generating helpful responses, enhancing their ability to assist users effectively.
|
| 105 |
+
|
| 106 |
+
## Data Structure
|
| 107 |
+
|
| 108 |
+
- **Format**: [Conversational](https://huggingface.co/docs/trl/main/dataset_formats#conversational)
|
| 109 |
+
- **Type**: [Preference](https://huggingface.co/docs/trl/main/dataset_formats#preference)
|
| 110 |
+
|
| 111 |
+
Columns:
|
| 112 |
+
- `"prompt"`: The user query.
|
| 113 |
+
- `"chosen"`: A response deemed helpful by human evaluators.
|
| 114 |
+
- `"rejected"`: A response considered less helpful or unhelpful.
|
| 115 |
+
|
| 116 |
+
This structure allows models to learn to prefer the _chosen_ response over the _rejected_ one, thereby aligning with human preferences in helpfulness.
|
| 117 |
+
|
| 118 |
+
## Generation script
|
| 119 |
+
|
| 120 |
+
The script used to generate this dataset can be found [here](https://github.com/huggingface/trl/blob/main/examples/datasets/hh-rlhf-helpful-base.py).
|
| 121 |
+
""")
|
| 122 |
+
|
| 123 |
+
if __name__ == "__main__":
|
| 124 |
+
parser = HfArgumentParser(ScriptArguments)
|
| 125 |
+
script_args = parser.parse_args_into_dataclasses()[0]
|
| 126 |
+
|
| 127 |
+
dataset = load_dataset("Anthropic/hh-rlhf", data_dir="helpful-base")
|
| 128 |
+
dataset = dataset.map(extract_dialogue, num_proc=script_args.dataset_num_proc)
|
| 129 |
+
|
| 130 |
+
if script_args.push_to_hub:
|
| 131 |
+
dataset.push_to_hub(script_args.repo_id)
|
| 132 |
+
model_card.push_to_hub(script_args.repo_id, repo_type="dataset")
|
tasks/tasksmith-1c108f674e97/tests/source/examples/datasets/llava_instruct_mix.py
ADDED
|
@@ -0,0 +1,118 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Copyright 2020-2026 The HuggingFace Team. All rights reserved.
|
| 2 |
+
#
|
| 3 |
+
# Licensed under the Apache License, Version 2.0 (the "License");
|
| 4 |
+
# you may not use this file except in compliance with the License.
|
| 5 |
+
# You may obtain a copy of the License at
|
| 6 |
+
#
|
| 7 |
+
# http://www.apache.org/licenses/LICENSE-2.0
|
| 8 |
+
#
|
| 9 |
+
# Unless required by applicable law or agreed to in writing, software
|
| 10 |
+
# distributed under the License is distributed on an "AS IS" BASIS,
|
| 11 |
+
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
| 12 |
+
# See the License for the specific language governing permissions and
|
| 13 |
+
# limitations under the License.
|
| 14 |
+
|
| 15 |
+
import ast
|
| 16 |
+
from dataclasses import dataclass, field
|
| 17 |
+
|
| 18 |
+
from datasets import load_dataset
|
| 19 |
+
from huggingface_hub import ModelCard
|
| 20 |
+
from transformers import HfArgumentParser
|
| 21 |
+
|
| 22 |
+
|
| 23 |
+
@dataclass
|
| 24 |
+
class ScriptArguments:
|
| 25 |
+
r"""
|
| 26 |
+
Arguments for the script.
|
| 27 |
+
|
| 28 |
+
Args:
|
| 29 |
+
push_to_hub (`bool`, *optional*, defaults to `False`):
|
| 30 |
+
Whether to push the dataset to the Hugging Face Hub.
|
| 31 |
+
repo_id (`str`, *optional*, defaults to `"trl-lib/llava-instruct-mix"`):
|
| 32 |
+
Hugging Face repository ID to push the dataset to.
|
| 33 |
+
dataset_num_proc (`int`, *optional*):
|
| 34 |
+
Number of workers to use for dataset processing.
|
| 35 |
+
"""
|
| 36 |
+
|
| 37 |
+
push_to_hub: bool = field(
|
| 38 |
+
default=False,
|
| 39 |
+
metadata={"help": "Whether to push the dataset to the Hugging Face Hub."},
|
| 40 |
+
)
|
| 41 |
+
repo_id: str = field(
|
| 42 |
+
default="trl-lib/llava-instruct-mix",
|
| 43 |
+
metadata={"help": "Hugging Face repository ID to push the dataset to."},
|
| 44 |
+
)
|
| 45 |
+
dataset_num_proc: int | None = field(
|
| 46 |
+
default=None,
|
| 47 |
+
metadata={"help": "Number of workers to use for dataset processing."},
|
| 48 |
+
)
|
| 49 |
+
|
| 50 |
+
|
| 51 |
+
def process_example(example):
|
| 52 |
+
messages = []
|
| 53 |
+
for message in ast.literal_eval(example["conversations"]):
|
| 54 |
+
content = message["value"]
|
| 55 |
+
content = content.replace("<image>", "").strip()
|
| 56 |
+
role = "user" if message["from"] == "human" else "assistant"
|
| 57 |
+
messages.append({"role": role, "content": content})
|
| 58 |
+
return {"messages": messages, "images": [example["image"]]}
|
| 59 |
+
|
| 60 |
+
|
| 61 |
+
def filter_long_examples(example):
|
| 62 |
+
total_length = sum(len(msg["content"]) for msg in example["messages"])
|
| 63 |
+
return total_length <= 1000
|
| 64 |
+
|
| 65 |
+
|
| 66 |
+
def split_prompt_completion(example):
|
| 67 |
+
"""
|
| 68 |
+
Splits the messages into a prompt and a completion. The last message is considered the completion.
|
| 69 |
+
"""
|
| 70 |
+
assert len(example["messages"]) > 1
|
| 71 |
+
example["prompt"] = example["messages"][:-1]
|
| 72 |
+
example["completion"] = example["messages"][-1:]
|
| 73 |
+
return example
|
| 74 |
+
|
| 75 |
+
|
| 76 |
+
model_card = ModelCard("""
|
| 77 |
+
---
|
| 78 |
+
tags: [trl]
|
| 79 |
+
---
|
| 80 |
+
|
| 81 |
+
# LLaVA Instruct Mix
|
| 82 |
+
|
| 83 |
+
## Summary
|
| 84 |
+
|
| 85 |
+
The LLaVA Instruct Mix dataset is a processed version of [LLaVA Instruct Mix](https://huggingface.co/datasets/theblackcat102/llava-instruct-mix).
|
| 86 |
+
|
| 87 |
+
## Data Structure
|
| 88 |
+
|
| 89 |
+
- **Format**: [Conversational](https://huggingface.co/docs/trl/main/dataset_formats#conversational)
|
| 90 |
+
- **Type**: [Language-modeling](https://huggingface.co/docs/trl/main/dataset_formats#language-modeling)
|
| 91 |
+
|
| 92 |
+
Columns:
|
| 93 |
+
- `"images"`: The image associated with the text.
|
| 94 |
+
- `"prompt"`: A list of messages that form the context for the conversation.
|
| 95 |
+
- `"completion"`: The last message in the conversation, which is the model's response.
|
| 96 |
+
|
| 97 |
+
This structure allows models to learn from the context of the conversation, enhancing their understanding of how to generate descriptive text based on visual inputs.
|
| 98 |
+
|
| 99 |
+
## Generation script
|
| 100 |
+
|
| 101 |
+
The script used to generate this dataset can be found [here](https://github.com/huggingface/trl/blob/main/examples/datasets/llava_instruct_mix.py).
|
| 102 |
+
""")
|
| 103 |
+
|
| 104 |
+
if __name__ == "__main__":
|
| 105 |
+
parser = HfArgumentParser(ScriptArguments)
|
| 106 |
+
script_args = parser.parse_args_into_dataclasses()[0]
|
| 107 |
+
|
| 108 |
+
dataset = load_dataset("theblackcat102/llava-instruct-mix", split="train", num_proc=script_args.dataset_num_proc)
|
| 109 |
+
|
| 110 |
+
dataset = dataset.map(
|
| 111 |
+
process_example, remove_columns=["conversations", "image"], num_proc=script_args.dataset_num_proc
|
| 112 |
+
)
|
| 113 |
+
dataset = dataset.filter(filter_long_examples, num_proc=script_args.dataset_num_proc)
|
| 114 |
+
dataset = dataset.map(split_prompt_completion, remove_columns=["messages"], num_proc=script_args.dataset_num_proc)
|
| 115 |
+
|
| 116 |
+
if script_args.push_to_hub:
|
| 117 |
+
dataset.push_to_hub(script_args.repo_id, num_proc=script_args.dataset_num_proc)
|
| 118 |
+
model_card.push_to_hub(script_args.repo_id, repo_type="dataset")
|
tasks/tasksmith-1c108f674e97/tests/source/examples/datasets/lm-human-preferences-descriptiveness.py
ADDED
|
@@ -0,0 +1,119 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Copyright 2020-2026 The HuggingFace Team. All rights reserved.
|
| 2 |
+
#
|
| 3 |
+
# Licensed under the Apache License, Version 2.0 (the "License");
|
| 4 |
+
# you may not use this file except in compliance with the License.
|
| 5 |
+
# You may obtain a copy of the License at
|
| 6 |
+
#
|
| 7 |
+
# http://www.apache.org/licenses/LICENSE-2.0
|
| 8 |
+
#
|
| 9 |
+
# Unless required by applicable law or agreed to in writing, software
|
| 10 |
+
# distributed under the License is distributed on an "AS IS" BASIS,
|
| 11 |
+
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
| 12 |
+
# See the License for the specific language governing permissions and
|
| 13 |
+
# limitations under the License.
|
| 14 |
+
|
| 15 |
+
from dataclasses import dataclass, field
|
| 16 |
+
|
| 17 |
+
from datasets import load_dataset
|
| 18 |
+
from huggingface_hub import ModelCard
|
| 19 |
+
from transformers import AutoTokenizer, HfArgumentParser
|
| 20 |
+
|
| 21 |
+
|
| 22 |
+
@dataclass
|
| 23 |
+
class ScriptArguments:
|
| 24 |
+
r"""
|
| 25 |
+
Arguments for the script.
|
| 26 |
+
|
| 27 |
+
Args:
|
| 28 |
+
push_to_hub (`bool`, *optional*, defaults to `False`):
|
| 29 |
+
Whether to push the dataset to the Hugging Face Hub.
|
| 30 |
+
repo_id (`str`, *optional*, defaults to `"trl-lib/lm-human-preferences-descriptiveness"`):
|
| 31 |
+
Hugging Face repository ID to push the dataset to.
|
| 32 |
+
dataset_num_proc (`int`, *optional*):
|
| 33 |
+
Number of workers to use for dataset processing.
|
| 34 |
+
"""
|
| 35 |
+
|
| 36 |
+
push_to_hub: bool = field(
|
| 37 |
+
default=False,
|
| 38 |
+
metadata={"help": "Whether to push the dataset to the Hugging Face Hub."},
|
| 39 |
+
)
|
| 40 |
+
repo_id: str = field(
|
| 41 |
+
default="trl-lib/lm-human-preferences-descriptiveness",
|
| 42 |
+
metadata={"help": "Hugging Face repository ID to push the dataset to."},
|
| 43 |
+
)
|
| 44 |
+
dataset_num_proc: int | None = field(
|
| 45 |
+
default=None,
|
| 46 |
+
metadata={"help": "Number of workers to use for dataset processing."},
|
| 47 |
+
)
|
| 48 |
+
|
| 49 |
+
|
| 50 |
+
# Edge cases handling: remove the cases where all samples are the same
|
| 51 |
+
def samples_not_all_same(example):
|
| 52 |
+
return not all(example["sample0"] == example[f"sample{j}"] for j in range(1, 4))
|
| 53 |
+
|
| 54 |
+
|
| 55 |
+
def to_prompt_completion(example, tokenizer):
|
| 56 |
+
prompt = tokenizer.decode(example["query"]).strip()
|
| 57 |
+
best_idx = example["best"]
|
| 58 |
+
chosen = tokenizer.decode(example[f"sample{best_idx}"])
|
| 59 |
+
for rejected_idx in range(4): # take the first rejected sample that is different from the chosen one
|
| 60 |
+
rejected = tokenizer.decode(example[f"sample{rejected_idx}"])
|
| 61 |
+
if chosen != rejected:
|
| 62 |
+
break
|
| 63 |
+
assert chosen != rejected
|
| 64 |
+
return {"prompt": prompt, "chosen": chosen, "rejected": rejected}
|
| 65 |
+
|
| 66 |
+
|
| 67 |
+
model_card = ModelCard("""
|
| 68 |
+
---
|
| 69 |
+
tags: [trl]
|
| 70 |
+
---
|
| 71 |
+
|
| 72 |
+
# LM-Human-Preferences-Descriptiveness Dataset
|
| 73 |
+
|
| 74 |
+
## Summary
|
| 75 |
+
|
| 76 |
+
The LM-Human-Preferences-Descriptiveness dataset is a processed subset of [OpenAI's LM-Human-Preferences](https://github.com/openai/lm-human-preferences), focusing specifically on enhancing the descriptiveness of generated text. It contains pairs of text samples, each labeled as either "chosen" or "rejected," based on human preferences regarding the level of detail and vividness in the descriptions. This dataset enables models to learn human preferences in descriptive language, improving their ability to generate rich and engaging narratives.
|
| 77 |
+
|
| 78 |
+
## Data Structure
|
| 79 |
+
|
| 80 |
+
- **Format**: [Standard](https://huggingface.co/docs/trl/main/dataset_formats#standard)
|
| 81 |
+
- **Type**: [Preference](https://huggingface.co/docs/trl/main/dataset_formats#preference)
|
| 82 |
+
|
| 83 |
+
Columns:
|
| 84 |
+
- `"prompt"`: The text sample.
|
| 85 |
+
- `"chosen"`: A version of the text with enhanced descriptiveness.
|
| 86 |
+
- `"rejected"`: A version of the text with less descriptiveness.
|
| 87 |
+
|
| 88 |
+
This structure allows models to learn to prefer the _chosen_ response over the _rejected_ one, thereby aligning with human preferences in descriptive language.
|
| 89 |
+
|
| 90 |
+
## Generation script
|
| 91 |
+
|
| 92 |
+
The script used to generate this dataset can be found [here](https://github.com/huggingface/trl/blob/main/examples/datasets/lm-human-preferences-descriptiveness.py).
|
| 93 |
+
""")
|
| 94 |
+
|
| 95 |
+
if __name__ == "__main__":
|
| 96 |
+
parser = HfArgumentParser(ScriptArguments)
|
| 97 |
+
script_args = parser.parse_args_into_dataclasses()[0]
|
| 98 |
+
|
| 99 |
+
dataset = load_dataset(
|
| 100 |
+
"json",
|
| 101 |
+
data_files="https://openaipublic.blob.core.windows.net/lm-human-preferences/labels/descriptiveness/offline_5k.json",
|
| 102 |
+
split="train",
|
| 103 |
+
)
|
| 104 |
+
|
| 105 |
+
dataset = dataset.filter(samples_not_all_same, num_proc=script_args.dataset_num_proc)
|
| 106 |
+
|
| 107 |
+
dataset = dataset.map(
|
| 108 |
+
to_prompt_completion,
|
| 109 |
+
num_proc=script_args.dataset_num_proc,
|
| 110 |
+
remove_columns=["query", "sample0", "sample1", "sample2", "sample3", "best"],
|
| 111 |
+
fn_kwargs={"tokenizer": AutoTokenizer.from_pretrained("gpt2")},
|
| 112 |
+
)
|
| 113 |
+
|
| 114 |
+
# train_size taken from https://github.com/openai/lm-human-preferences/blob/cbfd210bb8b08f6bc5c26878c10984b90f516c66/launch.py#L79)
|
| 115 |
+
dataset = dataset.train_test_split(train_size=4992)
|
| 116 |
+
|
| 117 |
+
if script_args.push_to_hub:
|
| 118 |
+
dataset.push_to_hub(script_args.repo_id)
|
| 119 |
+
model_card.push_to_hub(script_args.repo_id, repo_type="dataset")
|