


Stage Harbor release files 65501-66000
Browse filesThis view is limited to 50 files because it contains too many changes. See raw diff
- tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/pag.md +116 -0
- tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/paint_by_example.md +39 -0
- tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/panorama.md +54 -0
- tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/pia.md +171 -0
- tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/pix2pix.md +44 -0
- tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/pixart.md +148 -0
- tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/pixart_sigma.md +155 -0
- tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/sana.md +112 -0
- tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/sana_sprint.md +134 -0
- tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/self_attention_guidance.md +35 -0
- tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/semantic_stable_diffusion.md +35 -0
- tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/shap_e.md +37 -0
- tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/stable_audio.md +93 -0
- tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/stable_cascade.md +229 -0
- tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/stable_diffusion/adapter.md +47 -0
- tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/stable_diffusion/depth2img.md +44 -0
- tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/stable_diffusion/gligen.md +59 -0
- tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/stable_diffusion/image_variation.md +37 -0
- tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/stable_diffusion/img2img.md +59 -0
- tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/stable_diffusion/inpaint.md +61 -0
- tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/stable_diffusion/k_diffusion.md +27 -0
- tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/stable_diffusion/latent_upscale.md +38 -0
- tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/stable_diffusion/ldm3d_diffusion.md +59 -0
- tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/stable_diffusion/overview.md +216 -0
- tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/stable_diffusion/sdxl_turbo.md +35 -0
- tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/stable_diffusion/stable_diffusion_2.md +125 -0
- tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/stable_diffusion/stable_diffusion_3.md +452 -0
- tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/stable_diffusion/stable_diffusion_safe.md +61 -0
- tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/stable_diffusion/stable_diffusion_xl.md +60 -0
- tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/stable_diffusion/svd.md +43 -0
- tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/stable_diffusion/text2img.md +63 -0
- tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/stable_diffusion/upscale.md +41 -0
- tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/stable_unclip.md +133 -0
- tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/text_to_video.md +197 -0
- tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/text_to_video_zero.md +306 -0
- tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/unclip.md +37 -0
- tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/unidiffuser.md +209 -0
- tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/value_guided_sampling.md +38 -0
- tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/visualcloze.md +300 -0
- tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/wan.md +356 -0
- tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/wuerstchen.md +167 -0
- tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/quantization.md +46 -0
- tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/schedulers/cm_stochastic_iterative.md +27 -0
- tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/schedulers/consistency_decoder.md +21 -0
- tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/schedulers/cosine_dpm.md +24 -0
- tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/schedulers/ddim.md +82 -0
- tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/schedulers/ddim_cogvideox.md +19 -0
- tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/schedulers/ddim_inverse.md +19 -0
- tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/schedulers/ddpm.md +25 -0
- tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/schedulers/deis.md +34 -0
tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/pag.md
ADDED
|
@@ -0,0 +1,116 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Perturbed-Attention Guidance
|
| 14 |
+
|
| 15 |
+
<div class="flex flex-wrap space-x-1">
|
| 16 |
+
<img alt="LoRA" src="https://img.shields.io/badge/LoRA-d8b4fe?style=flat"/>
|
| 17 |
+
</div>
|
| 18 |
+
|
| 19 |
+
[Perturbed-Attention Guidance (PAG)](https://ku-cvlab.github.io/Perturbed-Attention-Guidance/) is a new diffusion sampling guidance that improves sample quality across both unconditional and conditional settings, achieving this without requiring further training or the integration of external modules.
|
| 20 |
+
|
| 21 |
+
PAG was introduced in [Self-Rectifying Diffusion Sampling with Perturbed-Attention Guidance](https://huggingface.co/papers/2403.17377) by Donghoon Ahn, Hyoungwon Cho, Jaewon Min, Wooseok Jang, Jungwoo Kim, SeonHwa Kim, Hyun Hee Park, Kyong Hwan Jin and Seungryong Kim.
|
| 22 |
+
|
| 23 |
+
The abstract from the paper is:
|
| 24 |
+
|
| 25 |
+
*Recent studies have demonstrated that diffusion models are capable of generating high-quality samples, but their quality heavily depends on sampling guidance techniques, such as classifier guidance (CG) and classifier-free guidance (CFG). These techniques are often not applicable in unconditional generation or in various downstream tasks such as image restoration. In this paper, we propose a novel sampling guidance, called Perturbed-Attention Guidance (PAG), which improves diffusion sample quality across both unconditional and conditional settings, achieving this without requiring additional training or the integration of external modules. PAG is designed to progressively enhance the structure of samples throughout the denoising process. It involves generating intermediate samples with degraded structure by substituting selected self-attention maps in diffusion U-Net with an identity matrix, by considering the self-attention mechanisms' ability to capture structural information, and guiding the denoising process away from these degraded samples. In both ADM and Stable Diffusion, PAG surprisingly improves sample quality in conditional and even unconditional scenarios. Moreover, PAG significantly improves the baseline performance in various downstream tasks where existing guidances such as CG or CFG cannot be fully utilized, including ControlNet with empty prompts and image restoration such as inpainting and deblurring.*
|
| 26 |
+
|
| 27 |
+
PAG can be used by specifying the `pag_applied_layers` as a parameter when instantiating a PAG pipeline. It can be a single string or a list of strings. Each string can be a unique layer identifier or a regular expression to identify one or more layers.
|
| 28 |
+
|
| 29 |
+
- Full identifier as a normal string: `down_blocks.2.attentions.0.transformer_blocks.0.attn1.processor`
|
| 30 |
+
- Full identifier as a RegEx: `down_blocks.2.(attentions|motion_modules).0.transformer_blocks.0.attn1.processor`
|
| 31 |
+
- Partial identifier as a RegEx: `down_blocks.2`, or `attn1`
|
| 32 |
+
- List of identifiers (can be combo of strings and ReGex): `["blocks.1", "blocks.(14|20)", r"down_blocks\.(2,3)"]`
|
| 33 |
+
|
| 34 |
+
<Tip warning={true}>
|
| 35 |
+
|
| 36 |
+
Since RegEx is supported as a way for matching layer identifiers, it is crucial to use it correctly otherwise there might be unexpected behaviour. The recommended way to use PAG is by specifying layers as `blocks.{layer_index}` and `blocks.({layer_index_1|layer_index_2|...})`. Using it in any other way, while doable, may bypass our basic validation checks and give you unexpected results.
|
| 37 |
+
|
| 38 |
+
</Tip>
|
| 39 |
+
|
| 40 |
+
## AnimateDiffPAGPipeline
|
| 41 |
+
[[autodoc]] AnimateDiffPAGPipeline
|
| 42 |
+
- all
|
| 43 |
+
- __call__
|
| 44 |
+
|
| 45 |
+
## HunyuanDiTPAGPipeline
|
| 46 |
+
[[autodoc]] HunyuanDiTPAGPipeline
|
| 47 |
+
- all
|
| 48 |
+
- __call__
|
| 49 |
+
|
| 50 |
+
## KolorsPAGPipeline
|
| 51 |
+
[[autodoc]] KolorsPAGPipeline
|
| 52 |
+
- all
|
| 53 |
+
- __call__
|
| 54 |
+
|
| 55 |
+
## StableDiffusionPAGInpaintPipeline
|
| 56 |
+
[[autodoc]] StableDiffusionPAGInpaintPipeline
|
| 57 |
+
- all
|
| 58 |
+
- __call__
|
| 59 |
+
|
| 60 |
+
## StableDiffusionPAGPipeline
|
| 61 |
+
[[autodoc]] StableDiffusionPAGPipeline
|
| 62 |
+
- all
|
| 63 |
+
- __call__
|
| 64 |
+
|
| 65 |
+
## StableDiffusionPAGImg2ImgPipeline
|
| 66 |
+
[[autodoc]] StableDiffusionPAGImg2ImgPipeline
|
| 67 |
+
- all
|
| 68 |
+
- __call__
|
| 69 |
+
|
| 70 |
+
## StableDiffusionControlNetPAGPipeline
|
| 71 |
+
[[autodoc]] StableDiffusionControlNetPAGPipeline
|
| 72 |
+
|
| 73 |
+
## StableDiffusionControlNetPAGInpaintPipeline
|
| 74 |
+
[[autodoc]] StableDiffusionControlNetPAGInpaintPipeline
|
| 75 |
+
- all
|
| 76 |
+
- __call__
|
| 77 |
+
|
| 78 |
+
## StableDiffusionXLPAGPipeline
|
| 79 |
+
[[autodoc]] StableDiffusionXLPAGPipeline
|
| 80 |
+
- all
|
| 81 |
+
- __call__
|
| 82 |
+
|
| 83 |
+
## StableDiffusionXLPAGImg2ImgPipeline
|
| 84 |
+
[[autodoc]] StableDiffusionXLPAGImg2ImgPipeline
|
| 85 |
+
- all
|
| 86 |
+
- __call__
|
| 87 |
+
|
| 88 |
+
## StableDiffusionXLPAGInpaintPipeline
|
| 89 |
+
[[autodoc]] StableDiffusionXLPAGInpaintPipeline
|
| 90 |
+
- all
|
| 91 |
+
- __call__
|
| 92 |
+
|
| 93 |
+
## StableDiffusionXLControlNetPAGPipeline
|
| 94 |
+
[[autodoc]] StableDiffusionXLControlNetPAGPipeline
|
| 95 |
+
- all
|
| 96 |
+
- __call__
|
| 97 |
+
|
| 98 |
+
## StableDiffusionXLControlNetPAGImg2ImgPipeline
|
| 99 |
+
[[autodoc]] StableDiffusionXLControlNetPAGImg2ImgPipeline
|
| 100 |
+
- all
|
| 101 |
+
- __call__
|
| 102 |
+
|
| 103 |
+
## StableDiffusion3PAGPipeline
|
| 104 |
+
[[autodoc]] StableDiffusion3PAGPipeline
|
| 105 |
+
- all
|
| 106 |
+
- __call__
|
| 107 |
+
|
| 108 |
+
## StableDiffusion3PAGImg2ImgPipeline
|
| 109 |
+
[[autodoc]] StableDiffusion3PAGImg2ImgPipeline
|
| 110 |
+
- all
|
| 111 |
+
- __call__
|
| 112 |
+
|
| 113 |
+
## PixArtSigmaPAGPipeline
|
| 114 |
+
[[autodoc]] PixArtSigmaPAGPipeline
|
| 115 |
+
- all
|
| 116 |
+
- __call__
|
tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/paint_by_example.md
ADDED
|
@@ -0,0 +1,39 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Paint by Example
|
| 14 |
+
|
| 15 |
+
[Paint by Example: Exemplar-based Image Editing with Diffusion Models](https://huggingface.co/papers/2211.13227) is by Binxin Yang, Shuyang Gu, Bo Zhang, Ting Zhang, Xuejin Chen, Xiaoyan Sun, Dong Chen, Fang Wen.
|
| 16 |
+
|
| 17 |
+
The abstract from the paper is:
|
| 18 |
+
|
| 19 |
+
*Language-guided image editing has achieved great success recently. In this paper, for the first time, we investigate exemplar-guided image editing for more precise control. We achieve this goal by leveraging self-supervised training to disentangle and re-organize the source image and the exemplar. However, the naive approach will cause obvious fusing artifacts. We carefully analyze it and propose an information bottleneck and strong augmentations to avoid the trivial solution of directly copying and pasting the exemplar image. Meanwhile, to ensure the controllability of the editing process, we design an arbitrary shape mask for the exemplar image and leverage the classifier-free guidance to increase the similarity to the exemplar image. The whole framework involves a single forward of the diffusion model without any iterative optimization. We demonstrate that our method achieves an impressive performance and enables controllable editing on in-the-wild images with high fidelity.*
|
| 20 |
+
|
| 21 |
+
The original codebase can be found at [Fantasy-Studio/Paint-by-Example](https://github.com/Fantasy-Studio/Paint-by-Example), and you can try it out in a [demo](https://huggingface.co/spaces/Fantasy-Studio/Paint-by-Example).
|
| 22 |
+
|
| 23 |
+
## Tips
|
| 24 |
+
|
| 25 |
+
Paint by Example is supported by the official [Fantasy-Studio/Paint-by-Example](https://huggingface.co/Fantasy-Studio/Paint-by-Example) checkpoint. The checkpoint is warm-started from [CompVis/stable-diffusion-v1-4](https://huggingface.co/CompVis/stable-diffusion-v1-4) to inpaint partly masked images conditioned on example and reference images.
|
| 26 |
+
|
| 27 |
+
<Tip>
|
| 28 |
+
|
| 29 |
+
Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines.
|
| 30 |
+
|
| 31 |
+
</Tip>
|
| 32 |
+
|
| 33 |
+
## PaintByExamplePipeline
|
| 34 |
+
[[autodoc]] PaintByExamplePipeline
|
| 35 |
+
- all
|
| 36 |
+
- __call__
|
| 37 |
+
|
| 38 |
+
## StableDiffusionPipelineOutput
|
| 39 |
+
[[autodoc]] pipelines.stable_diffusion.StableDiffusionPipelineOutput
|
tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/panorama.md
ADDED
|
@@ -0,0 +1,54 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# MultiDiffusion
|
| 14 |
+
|
| 15 |
+
<div class="flex flex-wrap space-x-1">
|
| 16 |
+
<img alt="LoRA" src="https://img.shields.io/badge/LoRA-d8b4fe?style=flat"/>
|
| 17 |
+
</div>
|
| 18 |
+
|
| 19 |
+
[MultiDiffusion: Fusing Diffusion Paths for Controlled Image Generation](https://huggingface.co/papers/2302.08113) is by Omer Bar-Tal, Lior Yariv, Yaron Lipman, and Tali Dekel.
|
| 20 |
+
|
| 21 |
+
The abstract from the paper is:
|
| 22 |
+
|
| 23 |
+
*Recent advances in text-to-image generation with diffusion models present transformative capabilities in image quality. However, user controllability of the generated image, and fast adaptation to new tasks still remains an open challenge, currently mostly addressed by costly and long re-training and fine-tuning or ad-hoc adaptations to specific image generation tasks. In this work, we present MultiDiffusion, a unified framework that enables versatile and controllable image generation, using a pre-trained text-to-image diffusion model, without any further training or finetuning. At the center of our approach is a new generation process, based on an optimization task that binds together multiple diffusion generation processes with a shared set of parameters or constraints. We show that MultiDiffusion can be readily applied to generate high quality and diverse images that adhere to user-provided controls, such as desired aspect ratio (e.g., panorama), and spatial guiding signals, ranging from tight segmentation masks to bounding boxes.*
|
| 24 |
+
|
| 25 |
+
You can find additional information about MultiDiffusion on the [project page](https://multidiffusion.github.io/), [original codebase](https://github.com/omerbt/MultiDiffusion), and try it out in a [demo](https://huggingface.co/spaces/weizmannscience/MultiDiffusion).
|
| 26 |
+
|
| 27 |
+
## Tips
|
| 28 |
+
|
| 29 |
+
While calling [`StableDiffusionPanoramaPipeline`], it's possible to specify the `view_batch_size` parameter to be > 1.
|
| 30 |
+
For some GPUs with high performance, this can speedup the generation process and increase VRAM usage.
|
| 31 |
+
|
| 32 |
+
To generate panorama-like images make sure you pass the width parameter accordingly. We recommend a width value of 2048 which is the default.
|
| 33 |
+
|
| 34 |
+
Circular padding is applied to ensure there are no stitching artifacts when working with panoramas to ensure a seamless transition from the rightmost part to the leftmost part. By enabling circular padding (set `circular_padding=True`), the operation applies additional crops after the rightmost point of the image, allowing the model to "see” the transition from the rightmost part to the leftmost part. This helps maintain visual consistency in a 360-degree sense and creates a proper “panorama” that can be viewed using 360-degree panorama viewers. When decoding latents in Stable Diffusion, circular padding is applied to ensure that the decoded latents match in the RGB space.
|
| 35 |
+
|
| 36 |
+
For example, without circular padding, there is a stitching artifact (default):
|
| 37 |
+
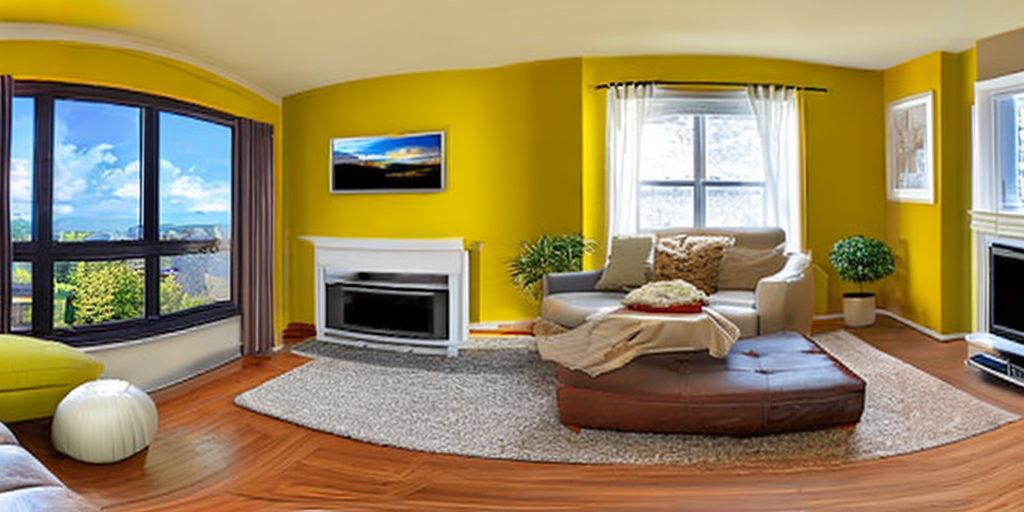
|
| 38 |
+
|
| 39 |
+
But with circular padding, the right and the left parts are matching (`circular_padding=True`):
|
| 40 |
+
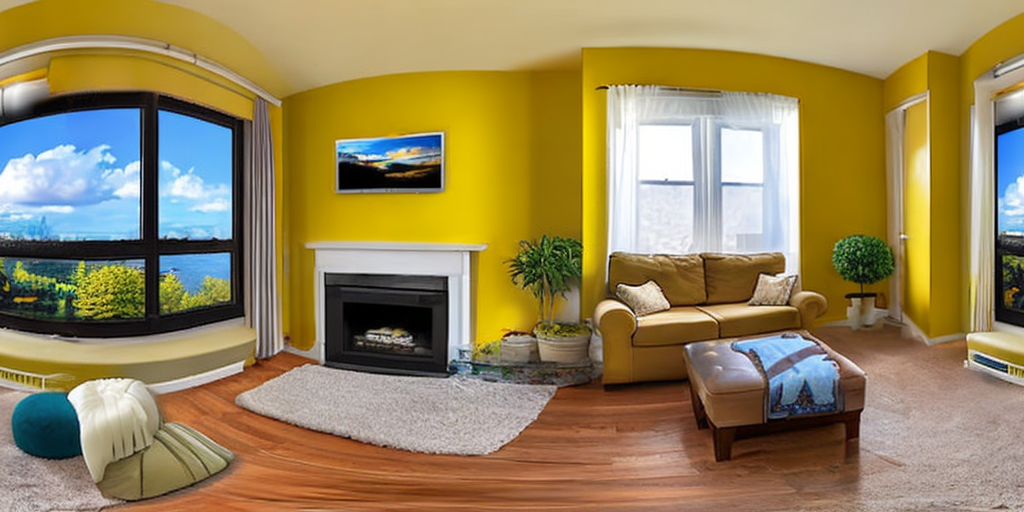
|
| 41 |
+
|
| 42 |
+
<Tip>
|
| 43 |
+
|
| 44 |
+
Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines.
|
| 45 |
+
|
| 46 |
+
</Tip>
|
| 47 |
+
|
| 48 |
+
## StableDiffusionPanoramaPipeline
|
| 49 |
+
[[autodoc]] StableDiffusionPanoramaPipeline
|
| 50 |
+
- __call__
|
| 51 |
+
- all
|
| 52 |
+
|
| 53 |
+
## StableDiffusionPipelineOutput
|
| 54 |
+
[[autodoc]] pipelines.stable_diffusion.StableDiffusionPipelineOutput
|
tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/pia.md
ADDED
|
@@ -0,0 +1,171 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Image-to-Video Generation with PIA (Personalized Image Animator)
|
| 14 |
+
|
| 15 |
+
<div class="flex flex-wrap space-x-1">
|
| 16 |
+
<img alt="LoRA" src="https://img.shields.io/badge/LoRA-d8b4fe?style=flat"/>
|
| 17 |
+
</div>
|
| 18 |
+
|
| 19 |
+
## Overview
|
| 20 |
+
|
| 21 |
+
[PIA: Your Personalized Image Animator via Plug-and-Play Modules in Text-to-Image Models](https://huggingface.co/papers/2312.13964) by Yiming Zhang, Zhening Xing, Yanhong Zeng, Youqing Fang, Kai Chen
|
| 22 |
+
|
| 23 |
+
Recent advancements in personalized text-to-image (T2I) models have revolutionized content creation, empowering non-experts to generate stunning images with unique styles. While promising, adding realistic motions into these personalized images by text poses significant challenges in preserving distinct styles, high-fidelity details, and achieving motion controllability by text. In this paper, we present PIA, a Personalized Image Animator that excels in aligning with condition images, achieving motion controllability by text, and the compatibility with various personalized T2I models without specific tuning. To achieve these goals, PIA builds upon a base T2I model with well-trained temporal alignment layers, allowing for the seamless transformation of any personalized T2I model into an image animation model. A key component of PIA is the introduction of the condition module, which utilizes the condition frame and inter-frame affinity as input to transfer appearance information guided by the affinity hint for individual frame synthesis in the latent space. This design mitigates the challenges of appearance-related image alignment within and allows for a stronger focus on aligning with motion-related guidance.
|
| 24 |
+
|
| 25 |
+
[Project page](https://pi-animator.github.io/)
|
| 26 |
+
|
| 27 |
+
## Available Pipelines
|
| 28 |
+
|
| 29 |
+
| Pipeline | Tasks | Demo
|
| 30 |
+
|---|---|:---:|
|
| 31 |
+
| [PIAPipeline](https://github.com/huggingface/diffusers/blob/main/src/diffusers/pipelines/pia/pipeline_pia.py) | *Image-to-Video Generation with PIA* |
|
| 32 |
+
|
| 33 |
+
## Available checkpoints
|
| 34 |
+
|
| 35 |
+
Motion Adapter checkpoints for PIA can be found under the [OpenMMLab org](https://huggingface.co/openmmlab/PIA-condition-adapter). These checkpoints are meant to work with any model based on Stable Diffusion 1.5
|
| 36 |
+
|
| 37 |
+
## Usage example
|
| 38 |
+
|
| 39 |
+
PIA works with a MotionAdapter checkpoint and a Stable Diffusion 1.5 model checkpoint. The MotionAdapter is a collection of Motion Modules that are responsible for adding coherent motion across image frames. These modules are applied after the Resnet and Attention blocks in the Stable Diffusion UNet. In addition to the motion modules, PIA also replaces the input convolution layer of the SD 1.5 UNet model with a 9 channel input convolution layer.
|
| 40 |
+
|
| 41 |
+
The following example demonstrates how to use PIA to generate a video from a single image.
|
| 42 |
+
|
| 43 |
+
```python
|
| 44 |
+
import torch
|
| 45 |
+
from diffusers import (
|
| 46 |
+
EulerDiscreteScheduler,
|
| 47 |
+
MotionAdapter,
|
| 48 |
+
PIAPipeline,
|
| 49 |
+
)
|
| 50 |
+
from diffusers.utils import export_to_gif, load_image
|
| 51 |
+
|
| 52 |
+
adapter = MotionAdapter.from_pretrained("openmmlab/PIA-condition-adapter")
|
| 53 |
+
pipe = PIAPipeline.from_pretrained("SG161222/Realistic_Vision_V6.0_B1_noVAE", motion_adapter=adapter, torch_dtype=torch.float16)
|
| 54 |
+
|
| 55 |
+
pipe.scheduler = EulerDiscreteScheduler.from_config(pipe.scheduler.config)
|
| 56 |
+
pipe.enable_model_cpu_offload()
|
| 57 |
+
pipe.enable_vae_slicing()
|
| 58 |
+
|
| 59 |
+
image = load_image(
|
| 60 |
+
"https://huggingface.co/datasets/hf-internal-testing/diffusers-images/resolve/main/pix2pix/cat_6.png?download=true"
|
| 61 |
+
)
|
| 62 |
+
image = image.resize((512, 512))
|
| 63 |
+
prompt = "cat in a field"
|
| 64 |
+
negative_prompt = "wrong white balance, dark, sketches,worst quality,low quality"
|
| 65 |
+
|
| 66 |
+
generator = torch.Generator("cpu").manual_seed(0)
|
| 67 |
+
output = pipe(image=image, prompt=prompt, generator=generator)
|
| 68 |
+
frames = output.frames[0]
|
| 69 |
+
export_to_gif(frames, "pia-animation.gif")
|
| 70 |
+
```
|
| 71 |
+
|
| 72 |
+
Here are some sample outputs:
|
| 73 |
+
|
| 74 |
+
<table>
|
| 75 |
+
<tr>
|
| 76 |
+
<td><center>
|
| 77 |
+
cat in a field.
|
| 78 |
+
<br>
|
| 79 |
+
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/pia-default-output.gif"
|
| 80 |
+
alt="cat in a field"
|
| 81 |
+
style="width: 300px;" />
|
| 82 |
+
</center></td>
|
| 83 |
+
</tr>
|
| 84 |
+
</table>
|
| 85 |
+
|
| 86 |
+
|
| 87 |
+
<Tip>
|
| 88 |
+
|
| 89 |
+
If you plan on using a scheduler that can clip samples, make sure to disable it by setting `clip_sample=False` in the scheduler as this can also have an adverse effect on generated samples. Additionally, the PIA checkpoints can be sensitive to the beta schedule of the scheduler. We recommend setting this to `linear`.
|
| 90 |
+
|
| 91 |
+
</Tip>
|
| 92 |
+
|
| 93 |
+
## Using FreeInit
|
| 94 |
+
|
| 95 |
+
[FreeInit: Bridging Initialization Gap in Video Diffusion Models](https://huggingface.co/papers/2312.07537) by Tianxing Wu, Chenyang Si, Yuming Jiang, Ziqi Huang, Ziwei Liu.
|
| 96 |
+
|
| 97 |
+
FreeInit is an effective method that improves temporal consistency and overall quality of videos generated using video-diffusion-models without any addition training. It can be applied to PIA, AnimateDiff, ModelScope, VideoCrafter and various other video generation models seamlessly at inference time, and works by iteratively refining the latent-initialization noise. More details can be found it the paper.
|
| 98 |
+
|
| 99 |
+
The following example demonstrates the usage of FreeInit.
|
| 100 |
+
|
| 101 |
+
```python
|
| 102 |
+
import torch
|
| 103 |
+
from diffusers import (
|
| 104 |
+
DDIMScheduler,
|
| 105 |
+
MotionAdapter,
|
| 106 |
+
PIAPipeline,
|
| 107 |
+
)
|
| 108 |
+
from diffusers.utils import export_to_gif, load_image
|
| 109 |
+
|
| 110 |
+
adapter = MotionAdapter.from_pretrained("openmmlab/PIA-condition-adapter")
|
| 111 |
+
pipe = PIAPipeline.from_pretrained("SG161222/Realistic_Vision_V6.0_B1_noVAE", motion_adapter=adapter)
|
| 112 |
+
|
| 113 |
+
# enable FreeInit
|
| 114 |
+
# Refer to the enable_free_init documentation for a full list of configurable parameters
|
| 115 |
+
pipe.enable_free_init(method="butterworth", use_fast_sampling=True)
|
| 116 |
+
|
| 117 |
+
# Memory saving options
|
| 118 |
+
pipe.enable_model_cpu_offload()
|
| 119 |
+
pipe.enable_vae_slicing()
|
| 120 |
+
|
| 121 |
+
pipe.scheduler = DDIMScheduler.from_config(pipe.scheduler.config)
|
| 122 |
+
image = load_image(
|
| 123 |
+
"https://huggingface.co/datasets/hf-internal-testing/diffusers-images/resolve/main/pix2pix/cat_6.png?download=true"
|
| 124 |
+
)
|
| 125 |
+
image = image.resize((512, 512))
|
| 126 |
+
prompt = "cat in a field"
|
| 127 |
+
negative_prompt = "wrong white balance, dark, sketches,worst quality,low quality"
|
| 128 |
+
|
| 129 |
+
generator = torch.Generator("cpu").manual_seed(0)
|
| 130 |
+
|
| 131 |
+
output = pipe(image=image, prompt=prompt, generator=generator)
|
| 132 |
+
frames = output.frames[0]
|
| 133 |
+
export_to_gif(frames, "pia-freeinit-animation.gif")
|
| 134 |
+
```
|
| 135 |
+
|
| 136 |
+
<table>
|
| 137 |
+
<tr>
|
| 138 |
+
<td><center>
|
| 139 |
+
cat in a field.
|
| 140 |
+
<br>
|
| 141 |
+
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/pia-freeinit-output-cat.gif"
|
| 142 |
+
alt="cat in a field"
|
| 143 |
+
style="width: 300px;" />
|
| 144 |
+
</center></td>
|
| 145 |
+
</tr>
|
| 146 |
+
</table>
|
| 147 |
+
|
| 148 |
+
|
| 149 |
+
<Tip warning={true}>
|
| 150 |
+
|
| 151 |
+
FreeInit is not really free - the improved quality comes at the cost of extra computation. It requires sampling a few extra times depending on the `num_iters` parameter that is set when enabling it. Setting the `use_fast_sampling` parameter to `True` can improve the overall performance (at the cost of lower quality compared to when `use_fast_sampling=False` but still better results than vanilla video generation models).
|
| 152 |
+
|
| 153 |
+
</Tip>
|
| 154 |
+
|
| 155 |
+
## PIAPipeline
|
| 156 |
+
|
| 157 |
+
[[autodoc]] PIAPipeline
|
| 158 |
+
- all
|
| 159 |
+
- __call__
|
| 160 |
+
- enable_freeu
|
| 161 |
+
- disable_freeu
|
| 162 |
+
- enable_free_init
|
| 163 |
+
- disable_free_init
|
| 164 |
+
- enable_vae_slicing
|
| 165 |
+
- disable_vae_slicing
|
| 166 |
+
- enable_vae_tiling
|
| 167 |
+
- disable_vae_tiling
|
| 168 |
+
|
| 169 |
+
## PIAPipelineOutput
|
| 170 |
+
|
| 171 |
+
[[autodoc]] pipelines.pia.PIAPipelineOutput
|
tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/pix2pix.md
ADDED
|
@@ -0,0 +1,44 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# InstructPix2Pix
|
| 14 |
+
|
| 15 |
+
<div class="flex flex-wrap space-x-1">
|
| 16 |
+
<img alt="LoRA" src="https://img.shields.io/badge/LoRA-d8b4fe?style=flat"/>
|
| 17 |
+
</div>
|
| 18 |
+
|
| 19 |
+
[InstructPix2Pix: Learning to Follow Image Editing Instructions](https://huggingface.co/papers/2211.09800) is by Tim Brooks, Aleksander Holynski and Alexei A. Efros.
|
| 20 |
+
|
| 21 |
+
The abstract from the paper is:
|
| 22 |
+
|
| 23 |
+
*We propose a method for editing images from human instructions: given an input image and a written instruction that tells the model what to do, our model follows these instructions to edit the image. To obtain training data for this problem, we combine the knowledge of two large pretrained models -- a language model (GPT-3) and a text-to-image model (Stable Diffusion) -- to generate a large dataset of image editing examples. Our conditional diffusion model, InstructPix2Pix, is trained on our generated data, and generalizes to real images and user-written instructions at inference time. Since it performs edits in the forward pass and does not require per example fine-tuning or inversion, our model edits images quickly, in a matter of seconds. We show compelling editing results for a diverse collection of input images and written instructions.*
|
| 24 |
+
|
| 25 |
+
You can find additional information about InstructPix2Pix on the [project page](https://www.timothybrooks.com/instruct-pix2pix), [original codebase](https://github.com/timothybrooks/instruct-pix2pix), and try it out in a [demo](https://huggingface.co/spaces/timbrooks/instruct-pix2pix).
|
| 26 |
+
|
| 27 |
+
<Tip>
|
| 28 |
+
|
| 29 |
+
Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines.
|
| 30 |
+
|
| 31 |
+
</Tip>
|
| 32 |
+
|
| 33 |
+
## StableDiffusionInstructPix2PixPipeline
|
| 34 |
+
[[autodoc]] StableDiffusionInstructPix2PixPipeline
|
| 35 |
+
- __call__
|
| 36 |
+
- all
|
| 37 |
+
- load_textual_inversion
|
| 38 |
+
- load_lora_weights
|
| 39 |
+
- save_lora_weights
|
| 40 |
+
|
| 41 |
+
## StableDiffusionXLInstructPix2PixPipeline
|
| 42 |
+
[[autodoc]] StableDiffusionXLInstructPix2PixPipeline
|
| 43 |
+
- __call__
|
| 44 |
+
- all
|
tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/pixart.md
ADDED
|
@@ -0,0 +1,148 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# PixArt-α
|
| 14 |
+
|
| 15 |
+
|
| 16 |
+
|
| 17 |
+
[PixArt-α: Fast Training of Diffusion Transformer for Photorealistic Text-to-Image Synthesis](https://huggingface.co/papers/2310.00426) is Junsong Chen, Jincheng Yu, Chongjian Ge, Lewei Yao, Enze Xie, Yue Wu, Zhongdao Wang, James Kwok, Ping Luo, Huchuan Lu, and Zhenguo Li.
|
| 18 |
+
|
| 19 |
+
The abstract from the paper is:
|
| 20 |
+
|
| 21 |
+
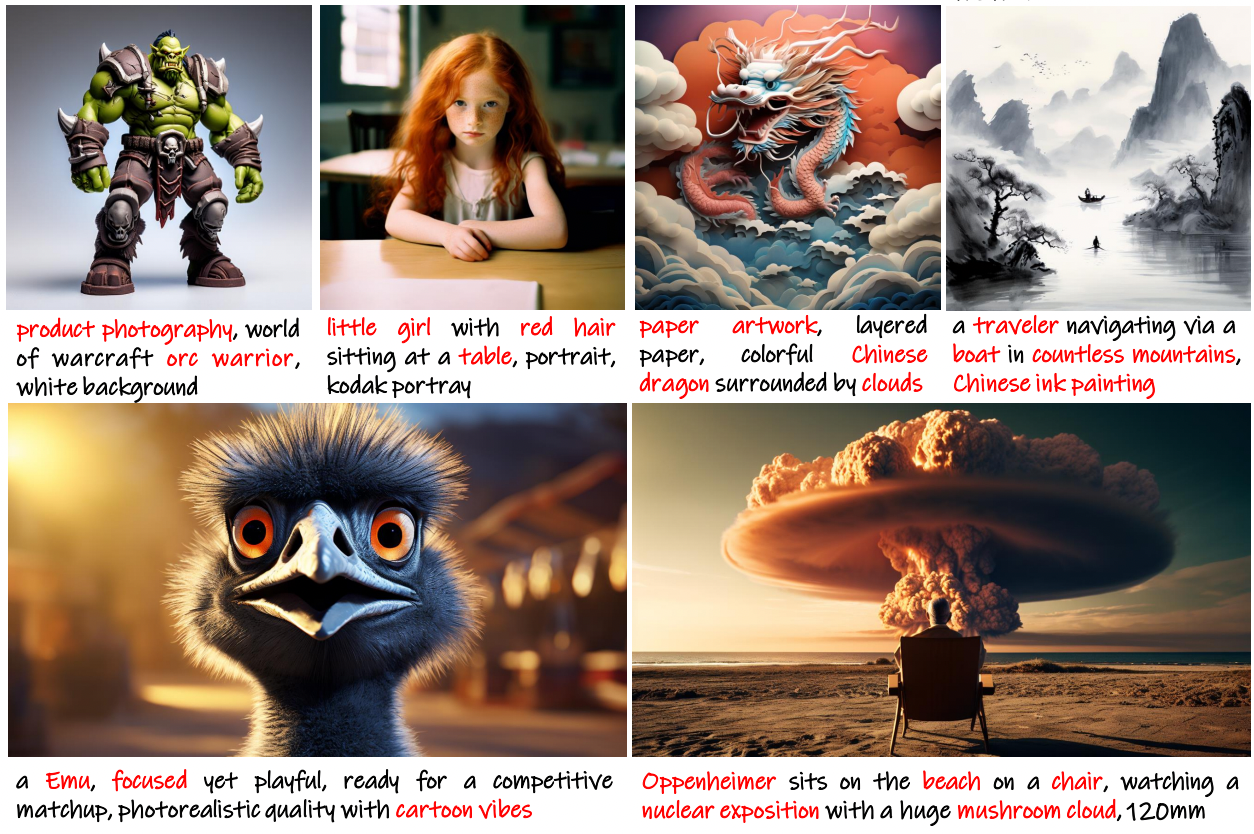
*The most advanced text-to-image (T2I) models require significant training costs (e.g., millions of GPU hours), seriously hindering the fundamental innovation for the AIGC community while increasing CO2 emissions. This paper introduces PIXART-α, a Transformer-based T2I diffusion model whose image generation quality is competitive with state-of-the-art image generators (e.g., Imagen, SDXL, and even Midjourney), reaching near-commercial application standards. Additionally, it supports high-resolution image synthesis up to 1024px resolution with low training cost, as shown in Figure 1 and 2. To achieve this goal, three core designs are proposed: (1) Training strategy decomposition: We devise three distinct training steps that separately optimize pixel dependency, text-image alignment, and image aesthetic quality; (2) Efficient T2I Transformer: We incorporate cross-attention modules into Diffusion Transformer (DiT) to inject text conditions and streamline the computation-intensive class-condition branch; (3) High-informative data: We emphasize the significance of concept density in text-image pairs and leverage a large Vision-Language model to auto-label dense pseudo-captions to assist text-image alignment learning. As a result, PIXART-α's training speed markedly surpasses existing large-scale T2I models, e.g., PIXART-α only takes 10.8% of Stable Diffusion v1.5's training time (675 vs. 6,250 A100 GPU days), saving nearly $300,000 ($26,000 vs. $320,000) and reducing 90% CO2 emissions. Moreover, compared with a larger SOTA model, RAPHAEL, our training cost is merely 1%. Extensive experiments demonstrate that PIXART-α excels in image quality, artistry, and semantic control. We hope PIXART-α will provide new insights to the AIGC community and startups to accelerate building their own high-quality yet low-cost generative models from scratch.*
|
| 22 |
+
|
| 23 |
+
You can find the original codebase at [PixArt-alpha/PixArt-alpha](https://github.com/PixArt-alpha/PixArt-alpha) and all the available checkpoints at [PixArt-alpha](https://huggingface.co/PixArt-alpha).
|
| 24 |
+
|
| 25 |
+
Some notes about this pipeline:
|
| 26 |
+
|
| 27 |
+
* It uses a Transformer backbone (instead of a UNet) for denoising. As such it has a similar architecture as [DiT](./dit).
|
| 28 |
+
* It was trained using text conditions computed from T5. This aspect makes the pipeline better at following complex text prompts with intricate details.
|
| 29 |
+
* It is good at producing high-resolution images at different aspect ratios. To get the best results, the authors recommend some size brackets which can be found [here](https://github.com/PixArt-alpha/PixArt-alpha/blob/08fbbd281ec96866109bdd2cdb75f2f58fb17610/diffusion/data/datasets/utils.py).
|
| 30 |
+
* It rivals the quality of state-of-the-art text-to-image generation systems (as of this writing) such as Stable Diffusion XL, Imagen, and DALL-E 2, while being more efficient than them.
|
| 31 |
+
|
| 32 |
+
<Tip>
|
| 33 |
+
|
| 34 |
+
Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines.
|
| 35 |
+
|
| 36 |
+
</Tip>
|
| 37 |
+
|
| 38 |
+
## Inference with under 8GB GPU VRAM
|
| 39 |
+
|
| 40 |
+
Run the [`PixArtAlphaPipeline`] with under 8GB GPU VRAM by loading the text encoder in 8-bit precision. Let's walk through a full-fledged example.
|
| 41 |
+
|
| 42 |
+
First, install the [bitsandbytes](https://github.com/TimDettmers/bitsandbytes) library:
|
| 43 |
+
|
| 44 |
+
```bash
|
| 45 |
+
pip install -U bitsandbytes
|
| 46 |
+
```
|
| 47 |
+
|
| 48 |
+
Then load the text encoder in 8-bit:
|
| 49 |
+
|
| 50 |
+
```python
|
| 51 |
+
from transformers import T5EncoderModel
|
| 52 |
+
from diffusers import PixArtAlphaPipeline
|
| 53 |
+
import torch
|
| 54 |
+
|
| 55 |
+
text_encoder = T5EncoderModel.from_pretrained(
|
| 56 |
+
"PixArt-alpha/PixArt-XL-2-1024-MS",
|
| 57 |
+
subfolder="text_encoder",
|
| 58 |
+
load_in_8bit=True,
|
| 59 |
+
device_map="auto",
|
| 60 |
+
|
| 61 |
+
)
|
| 62 |
+
pipe = PixArtAlphaPipeline.from_pretrained(
|
| 63 |
+
"PixArt-alpha/PixArt-XL-2-1024-MS",
|
| 64 |
+
text_encoder=text_encoder,
|
| 65 |
+
transformer=None,
|
| 66 |
+
device_map="auto"
|
| 67 |
+
)
|
| 68 |
+
```
|
| 69 |
+
|
| 70 |
+
Now, use the `pipe` to encode a prompt:
|
| 71 |
+
|
| 72 |
+
```python
|
| 73 |
+
with torch.no_grad():
|
| 74 |
+
prompt = "cute cat"
|
| 75 |
+
prompt_embeds, prompt_attention_mask, negative_embeds, negative_prompt_attention_mask = pipe.encode_prompt(prompt)
|
| 76 |
+
```
|
| 77 |
+
|
| 78 |
+
Since text embeddings have been computed, remove the `text_encoder` and `pipe` from the memory, and free up some GPU VRAM:
|
| 79 |
+
|
| 80 |
+
```python
|
| 81 |
+
import gc
|
| 82 |
+
|
| 83 |
+
def flush():
|
| 84 |
+
gc.collect()
|
| 85 |
+
torch.cuda.empty_cache()
|
| 86 |
+
|
| 87 |
+
del text_encoder
|
| 88 |
+
del pipe
|
| 89 |
+
flush()
|
| 90 |
+
```
|
| 91 |
+
|
| 92 |
+
Then compute the latents with the prompt embeddings as inputs:
|
| 93 |
+
|
| 94 |
+
```python
|
| 95 |
+
pipe = PixArtAlphaPipeline.from_pretrained(
|
| 96 |
+
"PixArt-alpha/PixArt-XL-2-1024-MS",
|
| 97 |
+
text_encoder=None,
|
| 98 |
+
torch_dtype=torch.float16,
|
| 99 |
+
).to("cuda")
|
| 100 |
+
|
| 101 |
+
latents = pipe(
|
| 102 |
+
negative_prompt=None,
|
| 103 |
+
prompt_embeds=prompt_embeds,
|
| 104 |
+
negative_prompt_embeds=negative_embeds,
|
| 105 |
+
prompt_attention_mask=prompt_attention_mask,
|
| 106 |
+
negative_prompt_attention_mask=negative_prompt_attention_mask,
|
| 107 |
+
num_images_per_prompt=1,
|
| 108 |
+
output_type="latent",
|
| 109 |
+
).images
|
| 110 |
+
|
| 111 |
+
del pipe.transformer
|
| 112 |
+
flush()
|
| 113 |
+
```
|
| 114 |
+
|
| 115 |
+
<Tip>
|
| 116 |
+
|
| 117 |
+
Notice that while initializing `pipe`, you're setting `text_encoder` to `None` so that it's not loaded.
|
| 118 |
+
|
| 119 |
+
</Tip>
|
| 120 |
+
|
| 121 |
+
Once the latents are computed, pass it off to the VAE to decode into a real image:
|
| 122 |
+
|
| 123 |
+
```python
|
| 124 |
+
with torch.no_grad():
|
| 125 |
+
image = pipe.vae.decode(latents / pipe.vae.config.scaling_factor, return_dict=False)[0]
|
| 126 |
+
image = pipe.image_processor.postprocess(image, output_type="pil")[0]
|
| 127 |
+
image.save("cat.png")
|
| 128 |
+
```
|
| 129 |
+
|
| 130 |
+
By deleting components you aren't using and flushing the GPU VRAM, you should be able to run [`PixArtAlphaPipeline`] with under 8GB GPU VRAM.
|
| 131 |
+
|
| 132 |
+
|
| 133 |
+
|
| 134 |
+
If you want a report of your memory-usage, run this [script](https://gist.github.com/sayakpaul/3ae0f847001d342af27018a96f467e4e).
|
| 135 |
+
|
| 136 |
+
<Tip warning={true}>
|
| 137 |
+
|
| 138 |
+
Text embeddings computed in 8-bit can impact the quality of the generated images because of the information loss in the representation space caused by the reduced precision. It's recommended to compare the outputs with and without 8-bit.
|
| 139 |
+
|
| 140 |
+
</Tip>
|
| 141 |
+
|
| 142 |
+
While loading the `text_encoder`, you set `load_in_8bit` to `True`. You could also specify `load_in_4bit` to bring your memory requirements down even further to under 7GB.
|
| 143 |
+
|
| 144 |
+
## PixArtAlphaPipeline
|
| 145 |
+
|
| 146 |
+
[[autodoc]] PixArtAlphaPipeline
|
| 147 |
+
- all
|
| 148 |
+
- __call__
|
tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/pixart_sigma.md
ADDED
|
@@ -0,0 +1,155 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# PixArt-Σ
|
| 14 |
+
|
| 15 |
+

|
| 16 |
+
|
| 17 |
+
[PixArt-Σ: Weak-to-Strong Training of Diffusion Transformer for 4K Text-to-Image Generation](https://huggingface.co/papers/2403.04692) is Junsong Chen, Jincheng Yu, Chongjian Ge, Lewei Yao, Enze Xie, Yue Wu, Zhongdao Wang, James Kwok, Ping Luo, Huchuan Lu, and Zhenguo Li.
|
| 18 |
+
|
| 19 |
+
The abstract from the paper is:
|
| 20 |
+
|
| 21 |
+
*In this paper, we introduce PixArt-Σ, a Diffusion Transformer model (DiT) capable of directly generating images at 4K resolution. PixArt-Σ represents a significant advancement over its predecessor, PixArt-α, offering images of markedly higher fidelity and improved alignment with text prompts. A key feature of PixArt-Σ is its training efficiency. Leveraging the foundational pre-training of PixArt-α, it evolves from the ‘weaker’ baseline to a ‘stronger’ model via incorporating higher quality data, a process we term “weak-to-strong training”. The advancements in PixArt-Σ are twofold: (1) High-Quality Training Data: PixArt-Σ incorporates superior-quality image data, paired with more precise and detailed image captions. (2) Efficient Token Compression: we propose a novel attention module within the DiT framework that compresses both keys and values, significantly improving efficiency and facilitating ultra-high-resolution image generation. Thanks to these improvements, PixArt-Σ achieves superior image quality and user prompt adherence capabilities with significantly smaller model size (0.6B parameters) than existing text-to-image diffusion models, such as SDXL (2.6B parameters) and SD Cascade (5.1B parameters). Moreover, PixArt-Σ’s capability to generate 4K images supports the creation of high-resolution posters and wallpapers, efficiently bolstering the production of highquality visual content in industries such as film and gaming.*
|
| 22 |
+
|
| 23 |
+
You can find the original codebase at [PixArt-alpha/PixArt-sigma](https://github.com/PixArt-alpha/PixArt-sigma) and all the available checkpoints at [PixArt-alpha](https://huggingface.co/PixArt-alpha).
|
| 24 |
+
|
| 25 |
+
Some notes about this pipeline:
|
| 26 |
+
|
| 27 |
+
* It uses a Transformer backbone (instead of a UNet) for denoising. As such it has a similar architecture as [DiT](https://hf.co/docs/transformers/model_doc/dit).
|
| 28 |
+
* It was trained using text conditions computed from T5. This aspect makes the pipeline better at following complex text prompts with intricate details.
|
| 29 |
+
* It is good at producing high-resolution images at different aspect ratios. To get the best results, the authors recommend some size brackets which can be found [here](https://github.com/PixArt-alpha/PixArt-sigma/blob/master/diffusion/data/datasets/utils.py).
|
| 30 |
+
* It rivals the quality of state-of-the-art text-to-image generation systems (as of this writing) such as PixArt-α, Stable Diffusion XL, Playground V2.0 and DALL-E 3, while being more efficient than them.
|
| 31 |
+
* It shows the ability of generating super high resolution images, such as 2048px or even 4K.
|
| 32 |
+
* It shows that text-to-image models can grow from a weak model to a stronger one through several improvements (VAEs, datasets, and so on.)
|
| 33 |
+
|
| 34 |
+
<Tip>
|
| 35 |
+
|
| 36 |
+
Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines.
|
| 37 |
+
|
| 38 |
+
</Tip>
|
| 39 |
+
|
| 40 |
+
<Tip>
|
| 41 |
+
|
| 42 |
+
You can further improve generation quality by passing the generated image from [`PixArtSigmaPipeline`] to the [SDXL refiner](../../using-diffusers/sdxl#base-to-refiner-model) model.
|
| 43 |
+
|
| 44 |
+
</Tip>
|
| 45 |
+
|
| 46 |
+
## Inference with under 8GB GPU VRAM
|
| 47 |
+
|
| 48 |
+
Run the [`PixArtSigmaPipeline`] with under 8GB GPU VRAM by loading the text encoder in 8-bit precision. Let's walk through a full-fledged example.
|
| 49 |
+
|
| 50 |
+
First, install the [bitsandbytes](https://github.com/TimDettmers/bitsandbytes) library:
|
| 51 |
+
|
| 52 |
+
```bash
|
| 53 |
+
pip install -U bitsandbytes
|
| 54 |
+
```
|
| 55 |
+
|
| 56 |
+
Then load the text encoder in 8-bit:
|
| 57 |
+
|
| 58 |
+
```python
|
| 59 |
+
from transformers import T5EncoderModel
|
| 60 |
+
from diffusers import PixArtSigmaPipeline
|
| 61 |
+
import torch
|
| 62 |
+
|
| 63 |
+
text_encoder = T5EncoderModel.from_pretrained(
|
| 64 |
+
"PixArt-alpha/PixArt-Sigma-XL-2-1024-MS",
|
| 65 |
+
subfolder="text_encoder",
|
| 66 |
+
load_in_8bit=True,
|
| 67 |
+
device_map="auto",
|
| 68 |
+
)
|
| 69 |
+
pipe = PixArtSigmaPipeline.from_pretrained(
|
| 70 |
+
"PixArt-alpha/PixArt-Sigma-XL-2-1024-MS",
|
| 71 |
+
text_encoder=text_encoder,
|
| 72 |
+
transformer=None,
|
| 73 |
+
device_map="balanced"
|
| 74 |
+
)
|
| 75 |
+
```
|
| 76 |
+
|
| 77 |
+
Now, use the `pipe` to encode a prompt:
|
| 78 |
+
|
| 79 |
+
```python
|
| 80 |
+
with torch.no_grad():
|
| 81 |
+
prompt = "cute cat"
|
| 82 |
+
prompt_embeds, prompt_attention_mask, negative_embeds, negative_prompt_attention_mask = pipe.encode_prompt(prompt)
|
| 83 |
+
```
|
| 84 |
+
|
| 85 |
+
Since text embeddings have been computed, remove the `text_encoder` and `pipe` from the memory, and free up some GPU VRAM:
|
| 86 |
+
|
| 87 |
+
```python
|
| 88 |
+
import gc
|
| 89 |
+
|
| 90 |
+
def flush():
|
| 91 |
+
gc.collect()
|
| 92 |
+
torch.cuda.empty_cache()
|
| 93 |
+
|
| 94 |
+
del text_encoder
|
| 95 |
+
del pipe
|
| 96 |
+
flush()
|
| 97 |
+
```
|
| 98 |
+
|
| 99 |
+
Then compute the latents with the prompt embeddings as inputs:
|
| 100 |
+
|
| 101 |
+
```python
|
| 102 |
+
pipe = PixArtSigmaPipeline.from_pretrained(
|
| 103 |
+
"PixArt-alpha/PixArt-Sigma-XL-2-1024-MS",
|
| 104 |
+
text_encoder=None,
|
| 105 |
+
torch_dtype=torch.float16,
|
| 106 |
+
).to("cuda")
|
| 107 |
+
|
| 108 |
+
latents = pipe(
|
| 109 |
+
negative_prompt=None,
|
| 110 |
+
prompt_embeds=prompt_embeds,
|
| 111 |
+
negative_prompt_embeds=negative_embeds,
|
| 112 |
+
prompt_attention_mask=prompt_attention_mask,
|
| 113 |
+
negative_prompt_attention_mask=negative_prompt_attention_mask,
|
| 114 |
+
num_images_per_prompt=1,
|
| 115 |
+
output_type="latent",
|
| 116 |
+
).images
|
| 117 |
+
|
| 118 |
+
del pipe.transformer
|
| 119 |
+
flush()
|
| 120 |
+
```
|
| 121 |
+
|
| 122 |
+
<Tip>
|
| 123 |
+
|
| 124 |
+
Notice that while initializing `pipe`, you're setting `text_encoder` to `None` so that it's not loaded.
|
| 125 |
+
|
| 126 |
+
</Tip>
|
| 127 |
+
|
| 128 |
+
Once the latents are computed, pass it off to the VAE to decode into a real image:
|
| 129 |
+
|
| 130 |
+
```python
|
| 131 |
+
with torch.no_grad():
|
| 132 |
+
image = pipe.vae.decode(latents / pipe.vae.config.scaling_factor, return_dict=False)[0]
|
| 133 |
+
image = pipe.image_processor.postprocess(image, output_type="pil")[0]
|
| 134 |
+
image.save("cat.png")
|
| 135 |
+
```
|
| 136 |
+
|
| 137 |
+
By deleting components you aren't using and flushing the GPU VRAM, you should be able to run [`PixArtSigmaPipeline`] with under 8GB GPU VRAM.
|
| 138 |
+
|
| 139 |
+

|
| 140 |
+
|
| 141 |
+
If you want a report of your memory-usage, run this [script](https://gist.github.com/sayakpaul/3ae0f847001d342af27018a96f467e4e).
|
| 142 |
+
|
| 143 |
+
<Tip warning={true}>
|
| 144 |
+
|
| 145 |
+
Text embeddings computed in 8-bit can impact the quality of the generated images because of the information loss in the representation space caused by the reduced precision. It's recommended to compare the outputs with and without 8-bit.
|
| 146 |
+
|
| 147 |
+
</Tip>
|
| 148 |
+
|
| 149 |
+
While loading the `text_encoder`, you set `load_in_8bit` to `True`. You could also specify `load_in_4bit` to bring your memory requirements down even further to under 7GB.
|
| 150 |
+
|
| 151 |
+
## PixArtSigmaPipeline
|
| 152 |
+
|
| 153 |
+
[[autodoc]] PixArtSigmaPipeline
|
| 154 |
+
- all
|
| 155 |
+
- __call__
|
tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/sana.md
ADDED
|
@@ -0,0 +1,112 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!-- Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
#
|
| 3 |
+
# Licensed under the Apache License, Version 2.0 (the "License");
|
| 4 |
+
# you may not use this file except in compliance with the License.
|
| 5 |
+
# You may obtain a copy of the License at
|
| 6 |
+
#
|
| 7 |
+
# http://www.apache.org/licenses/LICENSE-2.0
|
| 8 |
+
#
|
| 9 |
+
# Unless required by applicable law or agreed to in writing, software
|
| 10 |
+
# distributed under the License is distributed on an "AS IS" BASIS,
|
| 11 |
+
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
| 12 |
+
# See the License for the specific language governing permissions and
|
| 13 |
+
# limitations under the License. -->
|
| 14 |
+
|
| 15 |
+
# SanaPipeline
|
| 16 |
+
|
| 17 |
+
<div class="flex flex-wrap space-x-1">
|
| 18 |
+
<img alt="LoRA" src="https://img.shields.io/badge/LoRA-d8b4fe?style=flat"/>
|
| 19 |
+
<img alt="MPS" src="https://img.shields.io/badge/MPS-000000?style=flat&logo=apple&logoColor=white%22">
|
| 20 |
+
</div>
|
| 21 |
+
|
| 22 |
+
[SANA: Efficient High-Resolution Image Synthesis with Linear Diffusion Transformers](https://huggingface.co/papers/2410.10629) from NVIDIA and MIT HAN Lab, by Enze Xie, Junsong Chen, Junyu Chen, Han Cai, Haotian Tang, Yujun Lin, Zhekai Zhang, Muyang Li, Ligeng Zhu, Yao Lu, Song Han.
|
| 23 |
+
|
| 24 |
+
The abstract from the paper is:
|
| 25 |
+
|
| 26 |
+
*We introduce Sana, a text-to-image framework that can efficiently generate images up to 4096×4096 resolution. Sana can synthesize high-resolution, high-quality images with strong text-image alignment at a remarkably fast speed, deployable on laptop GPU. Core designs include: (1) Deep compression autoencoder: unlike traditional AEs, which compress images only 8×, we trained an AE that can compress images 32×, effectively reducing the number of latent tokens. (2) Linear DiT: we replace all vanilla attention in DiT with linear attention, which is more efficient at high resolutions without sacrificing quality. (3) Decoder-only text encoder: we replaced T5 with modern decoder-only small LLM as the text encoder and designed complex human instruction with in-context learning to enhance the image-text alignment. (4) Efficient training and sampling: we propose Flow-DPM-Solver to reduce sampling steps, with efficient caption labeling and selection to accelerate convergence. As a result, Sana-0.6B is very competitive with modern giant diffusion model (e.g. Flux-12B), being 20 times smaller and 100+ times faster in measured throughput. Moreover, Sana-0.6B can be deployed on a 16GB laptop GPU, taking less than 1 second to generate a 1024×1024 resolution image. Sana enables content creation at low cost. Code and model will be publicly released.*
|
| 27 |
+
|
| 28 |
+
<Tip>
|
| 29 |
+
|
| 30 |
+
Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines.
|
| 31 |
+
|
| 32 |
+
</Tip>
|
| 33 |
+
|
| 34 |
+
This pipeline was contributed by [lawrence-cj](https://github.com/lawrence-cj) and [chenjy2003](https://github.com/chenjy2003). The original codebase can be found [here](https://github.com/NVlabs/Sana). The original weights can be found under [hf.co/Efficient-Large-Model](https://huggingface.co/Efficient-Large-Model).
|
| 35 |
+
|
| 36 |
+
Available models:
|
| 37 |
+
|
| 38 |
+
| Model | Recommended dtype |
|
| 39 |
+
|:-----:|:-----------------:|
|
| 40 |
+
| [`Efficient-Large-Model/Sana_1600M_1024px_BF16_diffusers`](https://huggingface.co/Efficient-Large-Model/Sana_1600M_1024px_BF16_diffusers) | `torch.bfloat16` |
|
| 41 |
+
| [`Efficient-Large-Model/Sana_1600M_1024px_diffusers`](https://huggingface.co/Efficient-Large-Model/Sana_1600M_1024px_diffusers) | `torch.float16` |
|
| 42 |
+
| [`Efficient-Large-Model/Sana_1600M_1024px_MultiLing_diffusers`](https://huggingface.co/Efficient-Large-Model/Sana_1600M_1024px_MultiLing_diffusers) | `torch.float16` |
|
| 43 |
+
| [`Efficient-Large-Model/Sana_1600M_512px_diffusers`](https://huggingface.co/Efficient-Large-Model/Sana_1600M_512px_diffusers) | `torch.float16` |
|
| 44 |
+
| [`Efficient-Large-Model/Sana_1600M_512px_MultiLing_diffusers`](https://huggingface.co/Efficient-Large-Model/Sana_1600M_512px_MultiLing_diffusers) | `torch.float16` |
|
| 45 |
+
| [`Efficient-Large-Model/Sana_600M_1024px_diffusers`](https://huggingface.co/Efficient-Large-Model/Sana_600M_1024px_diffusers) | `torch.float16` |
|
| 46 |
+
| [`Efficient-Large-Model/Sana_600M_512px_diffusers`](https://huggingface.co/Efficient-Large-Model/Sana_600M_512px_diffusers) | `torch.float16` |
|
| 47 |
+
|
| 48 |
+
Refer to [this](https://huggingface.co/collections/Efficient-Large-Model/sana-673efba2a57ed99843f11f9e) collection for more information.
|
| 49 |
+
|
| 50 |
+
Note: The recommended dtype mentioned is for the transformer weights. The text encoder and VAE weights must stay in `torch.bfloat16` or `torch.float32` for the model to work correctly. Please refer to the inference example below to see how to load the model with the recommended dtype.
|
| 51 |
+
|
| 52 |
+
<Tip>
|
| 53 |
+
|
| 54 |
+
Make sure to pass the `variant` argument for downloaded checkpoints to use lower disk space. Set it to `"fp16"` for models with recommended dtype as `torch.float16`, and `"bf16"` for models with recommended dtype as `torch.bfloat16`. By default, `torch.float32` weights are downloaded, which use twice the amount of disk storage. Additionally, `torch.float32` weights can be downcasted on-the-fly by specifying the `torch_dtype` argument. Read about it in the [docs](https://huggingface.co/docs/diffusers/v0.31.0/en/api/pipelines/overview#diffusers.DiffusionPipeline.from_pretrained).
|
| 55 |
+
|
| 56 |
+
</Tip>
|
| 57 |
+
|
| 58 |
+
## Quantization
|
| 59 |
+
|
| 60 |
+
Quantization helps reduce the memory requirements of very large models by storing model weights in a lower precision data type. However, quantization may have varying impact on video quality depending on the video model.
|
| 61 |
+
|
| 62 |
+
Refer to the [Quantization](../../quantization/overview) overview to learn more about supported quantization backends and selecting a quantization backend that supports your use case. The example below demonstrates how to load a quantized [`SanaPipeline`] for inference with bitsandbytes.
|
| 63 |
+
|
| 64 |
+
```py
|
| 65 |
+
import torch
|
| 66 |
+
from diffusers import BitsAndBytesConfig as DiffusersBitsAndBytesConfig, SanaTransformer2DModel, SanaPipeline
|
| 67 |
+
from transformers import BitsAndBytesConfig as BitsAndBytesConfig, AutoModel
|
| 68 |
+
|
| 69 |
+
quant_config = BitsAndBytesConfig(load_in_8bit=True)
|
| 70 |
+
text_encoder_8bit = AutoModel.from_pretrained(
|
| 71 |
+
"Efficient-Large-Model/Sana_1600M_1024px_diffusers",
|
| 72 |
+
subfolder="text_encoder",
|
| 73 |
+
quantization_config=quant_config,
|
| 74 |
+
torch_dtype=torch.float16,
|
| 75 |
+
)
|
| 76 |
+
|
| 77 |
+
quant_config = DiffusersBitsAndBytesConfig(load_in_8bit=True)
|
| 78 |
+
transformer_8bit = SanaTransformer2DModel.from_pretrained(
|
| 79 |
+
"Efficient-Large-Model/Sana_1600M_1024px_diffusers",
|
| 80 |
+
subfolder="transformer",
|
| 81 |
+
quantization_config=quant_config,
|
| 82 |
+
torch_dtype=torch.float16,
|
| 83 |
+
)
|
| 84 |
+
|
| 85 |
+
pipeline = SanaPipeline.from_pretrained(
|
| 86 |
+
"Efficient-Large-Model/Sana_1600M_1024px_diffusers",
|
| 87 |
+
text_encoder=text_encoder_8bit,
|
| 88 |
+
transformer=transformer_8bit,
|
| 89 |
+
torch_dtype=torch.float16,
|
| 90 |
+
device_map="balanced",
|
| 91 |
+
)
|
| 92 |
+
|
| 93 |
+
prompt = "a tiny astronaut hatching from an egg on the moon"
|
| 94 |
+
image = pipeline(prompt).images[0]
|
| 95 |
+
image.save("sana.png")
|
| 96 |
+
```
|
| 97 |
+
|
| 98 |
+
## SanaPipeline
|
| 99 |
+
|
| 100 |
+
[[autodoc]] SanaPipeline
|
| 101 |
+
- all
|
| 102 |
+
- __call__
|
| 103 |
+
|
| 104 |
+
## SanaPAGPipeline
|
| 105 |
+
|
| 106 |
+
[[autodoc]] SanaPAGPipeline
|
| 107 |
+
- all
|
| 108 |
+
- __call__
|
| 109 |
+
|
| 110 |
+
## SanaPipelineOutput
|
| 111 |
+
|
| 112 |
+
[[autodoc]] pipelines.sana.pipeline_output.SanaPipelineOutput
|
tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/sana_sprint.md
ADDED
|
@@ -0,0 +1,134 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!-- Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
#
|
| 3 |
+
# Licensed under the Apache License, Version 2.0 (the "License");
|
| 4 |
+
# you may not use this file except in compliance with the License.
|
| 5 |
+
# You may obtain a copy of the License at
|
| 6 |
+
#
|
| 7 |
+
# http://www.apache.org/licenses/LICENSE-2.0
|
| 8 |
+
#
|
| 9 |
+
# Unless required by applicable law or agreed to in writing, software
|
| 10 |
+
# distributed under the License is distributed on an "AS IS" BASIS,
|
| 11 |
+
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
| 12 |
+
# See the License for the specific language governing permissions and
|
| 13 |
+
# limitations under the License. -->
|
| 14 |
+
|
| 15 |
+
# SANA-Sprint
|
| 16 |
+
|
| 17 |
+
<div class="flex flex-wrap space-x-1">
|
| 18 |
+
<img alt="LoRA" src="https://img.shields.io/badge/LoRA-d8b4fe?style=flat"/>
|
| 19 |
+
</div>
|
| 20 |
+
|
| 21 |
+
[SANA-Sprint: One-Step Diffusion with Continuous-Time Consistency Distillation](https://huggingface.co/papers/2503.09641) from NVIDIA, MIT HAN Lab, and Hugging Face by Junsong Chen, Shuchen Xue, Yuyang Zhao, Jincheng Yu, Sayak Paul, Junyu Chen, Han Cai, Enze Xie, Song Han
|
| 22 |
+
|
| 23 |
+
The abstract from the paper is:
|
| 24 |
+
|
| 25 |
+
*This paper presents SANA-Sprint, an efficient diffusion model for ultra-fast text-to-image (T2I) generation. SANA-Sprint is built on a pre-trained foundation model and augmented with hybrid distillation, dramatically reducing inference steps from 20 to 1-4. We introduce three key innovations: (1) We propose a training-free approach that transforms a pre-trained flow-matching model for continuous-time consistency distillation (sCM), eliminating costly training from scratch and achieving high training efficiency. Our hybrid distillation strategy combines sCM with latent adversarial distillation (LADD): sCM ensures alignment with the teacher model, while LADD enhances single-step generation fidelity. (2) SANA-Sprint is a unified step-adaptive model that achieves high-quality generation in 1-4 steps, eliminating step-specific training and improving efficiency. (3) We integrate ControlNet with SANA-Sprint for real-time interactive image generation, enabling instant visual feedback for user interaction. SANA-Sprint establishes a new Pareto frontier in speed-quality tradeoffs, achieving state-of-the-art performance with 7.59 FID and 0.74 GenEval in only 1 step — outperforming FLUX-schnell (7.94 FID / 0.71 GenEval) while being 10× faster (0.1s vs 1.1s on H100). It also achieves 0.1s (T2I) and 0.25s (ControlNet) latency for 1024×1024 images on H100, and 0.31s (T2I) on an RTX 4090, showcasing its exceptional efficiency and potential for AI-powered consumer applications (AIPC). Code and pre-trained models will be open-sourced.*
|
| 26 |
+
|
| 27 |
+
<Tip>
|
| 28 |
+
|
| 29 |
+
Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines.
|
| 30 |
+
|
| 31 |
+
</Tip>
|
| 32 |
+
|
| 33 |
+
This pipeline was contributed by [lawrence-cj](https://github.com/lawrence-cj), [shuchen Xue](https://github.com/scxue) and [Enze Xie](https://github.com/xieenze). The original codebase can be found [here](https://github.com/NVlabs/Sana). The original weights can be found under [hf.co/Efficient-Large-Model](https://huggingface.co/Efficient-Large-Model/).
|
| 34 |
+
|
| 35 |
+
Available models:
|
| 36 |
+
|
| 37 |
+
| Model | Recommended dtype |
|
| 38 |
+
|:-------------------------------------------------------------------------------------------------------------------------------------------:|:-----------------:|
|
| 39 |
+
| [`Efficient-Large-Model/Sana_Sprint_1.6B_1024px_diffusers`](https://huggingface.co/Efficient-Large-Model/Sana_Sprint_1.6B_1024px_diffusers) | `torch.bfloat16` |
|
| 40 |
+
| [`Efficient-Large-Model/Sana_Sprint_0.6B_1024px_diffusers`](https://huggingface.co/Efficient-Large-Model/Sana_Sprint_0.6B_1024px_diffusers) | `torch.bfloat16` |
|
| 41 |
+
|
| 42 |
+
Refer to [this](https://huggingface.co/collections/Efficient-Large-Model/sana-sprint-67d6810d65235085b3b17c76) collection for more information.
|
| 43 |
+
|
| 44 |
+
Note: The recommended dtype mentioned is for the transformer weights. The text encoder must stay in `torch.bfloat16` and VAE weights must stay in `torch.bfloat16` or `torch.float32` for the model to work correctly. Please refer to the inference example below to see how to load the model with the recommended dtype.
|
| 45 |
+
|
| 46 |
+
|
| 47 |
+
## Quantization
|
| 48 |
+
|
| 49 |
+
Quantization helps reduce the memory requirements of very large models by storing model weights in a lower precision data type. However, quantization may have varying impact on video quality depending on the video model.
|
| 50 |
+
|
| 51 |
+
Refer to the [Quantization](../../quantization/overview) overview to learn more about supported quantization backends and selecting a quantization backend that supports your use case. The example below demonstrates how to load a quantized [`SanaSprintPipeline`] for inference with bitsandbytes.
|
| 52 |
+
|
| 53 |
+
```py
|
| 54 |
+
import torch
|
| 55 |
+
from diffusers import BitsAndBytesConfig as DiffusersBitsAndBytesConfig, SanaTransformer2DModel, SanaSprintPipeline
|
| 56 |
+
from transformers import BitsAndBytesConfig as BitsAndBytesConfig, AutoModel
|
| 57 |
+
|
| 58 |
+
quant_config = BitsAndBytesConfig(load_in_8bit=True)
|
| 59 |
+
text_encoder_8bit = AutoModel.from_pretrained(
|
| 60 |
+
"Efficient-Large-Model/Sana_Sprint_1.6B_1024px_diffusers",
|
| 61 |
+
subfolder="text_encoder",
|
| 62 |
+
quantization_config=quant_config,
|
| 63 |
+
torch_dtype=torch.bfloat16,
|
| 64 |
+
)
|
| 65 |
+
|
| 66 |
+
quant_config = DiffusersBitsAndBytesConfig(load_in_8bit=True)
|
| 67 |
+
transformer_8bit = SanaTransformer2DModel.from_pretrained(
|
| 68 |
+
"Efficient-Large-Model/Sana_Sprint_1.6B_1024px_diffusers",
|
| 69 |
+
subfolder="transformer",
|
| 70 |
+
quantization_config=quant_config,
|
| 71 |
+
torch_dtype=torch.bfloat16,
|
| 72 |
+
)
|
| 73 |
+
|
| 74 |
+
pipeline = SanaSprintPipeline.from_pretrained(
|
| 75 |
+
"Efficient-Large-Model/Sana_Sprint_1.6B_1024px_diffusers",
|
| 76 |
+
text_encoder=text_encoder_8bit,
|
| 77 |
+
transformer=transformer_8bit,
|
| 78 |
+
torch_dtype=torch.bfloat16,
|
| 79 |
+
device_map="balanced",
|
| 80 |
+
)
|
| 81 |
+
|
| 82 |
+
prompt = "a tiny astronaut hatching from an egg on the moon"
|
| 83 |
+
image = pipeline(prompt).images[0]
|
| 84 |
+
image.save("sana.png")
|
| 85 |
+
```
|
| 86 |
+
|
| 87 |
+
## Setting `max_timesteps`
|
| 88 |
+
|
| 89 |
+
Users can tweak the `max_timesteps` value for experimenting with the visual quality of the generated outputs. The default `max_timesteps` value was obtained with an inference-time search process. For more details about it, check out the paper.
|
| 90 |
+
|
| 91 |
+
## Image to Image
|
| 92 |
+
|
| 93 |
+
The [`SanaSprintImg2ImgPipeline`] is a pipeline for image-to-image generation. It takes an input image and a prompt, and generates a new image based on the input image and the prompt.
|
| 94 |
+
|
| 95 |
+
```py
|
| 96 |
+
import torch
|
| 97 |
+
from diffusers import SanaSprintImg2ImgPipeline
|
| 98 |
+
from diffusers.utils.loading_utils import load_image
|
| 99 |
+
|
| 100 |
+
image = load_image(
|
| 101 |
+
"https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/penguin.png"
|
| 102 |
+
)
|
| 103 |
+
|
| 104 |
+
pipe = SanaSprintImg2ImgPipeline.from_pretrained(
|
| 105 |
+
"Efficient-Large-Model/Sana_Sprint_1.6B_1024px_diffusers",
|
| 106 |
+
torch_dtype=torch.bfloat16)
|
| 107 |
+
pipe.to("cuda")
|
| 108 |
+
|
| 109 |
+
image = pipe(
|
| 110 |
+
prompt="a cute pink bear",
|
| 111 |
+
image=image,
|
| 112 |
+
strength=0.5,
|
| 113 |
+
height=832,
|
| 114 |
+
width=480
|
| 115 |
+
).images[0]
|
| 116 |
+
image.save("output.png")
|
| 117 |
+
```
|
| 118 |
+
|
| 119 |
+
## SanaSprintPipeline
|
| 120 |
+
|
| 121 |
+
[[autodoc]] SanaSprintPipeline
|
| 122 |
+
- all
|
| 123 |
+
- __call__
|
| 124 |
+
|
| 125 |
+
## SanaSprintImg2ImgPipeline
|
| 126 |
+
|
| 127 |
+
[[autodoc]] SanaSprintImg2ImgPipeline
|
| 128 |
+
- all
|
| 129 |
+
- __call__
|
| 130 |
+
|
| 131 |
+
|
| 132 |
+
## SanaPipelineOutput
|
| 133 |
+
|
| 134 |
+
[[autodoc]] pipelines.sana.pipeline_output.SanaPipelineOutput
|
tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/self_attention_guidance.md
ADDED
|
@@ -0,0 +1,35 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Self-Attention Guidance
|
| 14 |
+
|
| 15 |
+
[Improving Sample Quality of Diffusion Models Using Self-Attention Guidance](https://huggingface.co/papers/2210.00939) is by Susung Hong et al.
|
| 16 |
+
|
| 17 |
+
The abstract from the paper is:
|
| 18 |
+
|
| 19 |
+
*Denoising diffusion models (DDMs) have attracted attention for their exceptional generation quality and diversity. This success is largely attributed to the use of class- or text-conditional diffusion guidance methods, such as classifier and classifier-free guidance. In this paper, we present a more comprehensive perspective that goes beyond the traditional guidance methods. From this generalized perspective, we introduce novel condition- and training-free strategies to enhance the quality of generated images. As a simple solution, blur guidance improves the suitability of intermediate samples for their fine-scale information and structures, enabling diffusion models to generate higher quality samples with a moderate guidance scale. Improving upon this, Self-Attention Guidance (SAG) uses the intermediate self-attention maps of diffusion models to enhance their stability and efficacy. Specifically, SAG adversarially blurs only the regions that diffusion models attend to at each iteration and guides them accordingly. Our experimental results show that our SAG improves the performance of various diffusion models, including ADM, IDDPM, Stable Diffusion, and DiT. Moreover, combining SAG with conventional guidance methods leads to further improvement.*
|
| 20 |
+
|
| 21 |
+
You can find additional information about Self-Attention Guidance on the [project page](https://ku-cvlab.github.io/Self-Attention-Guidance), [original codebase](https://github.com/KU-CVLAB/Self-Attention-Guidance), and try it out in a [demo](https://huggingface.co/spaces/susunghong/Self-Attention-Guidance) or [notebook](https://colab.research.google.com/github/SusungHong/Self-Attention-Guidance/blob/main/SAG_Stable.ipynb).
|
| 22 |
+
|
| 23 |
+
<Tip>
|
| 24 |
+
|
| 25 |
+
Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines.
|
| 26 |
+
|
| 27 |
+
</Tip>
|
| 28 |
+
|
| 29 |
+
## StableDiffusionSAGPipeline
|
| 30 |
+
[[autodoc]] StableDiffusionSAGPipeline
|
| 31 |
+
- __call__
|
| 32 |
+
- all
|
| 33 |
+
|
| 34 |
+
## StableDiffusionOutput
|
| 35 |
+
[[autodoc]] pipelines.stable_diffusion.StableDiffusionPipelineOutput
|
tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/semantic_stable_diffusion.md
ADDED
|
@@ -0,0 +1,35 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Semantic Guidance
|
| 14 |
+
|
| 15 |
+
Semantic Guidance for Diffusion Models was proposed in [SEGA: Instructing Text-to-Image Models using Semantic Guidance](https://huggingface.co/papers/2301.12247) and provides strong semantic control over image generation.
|
| 16 |
+
Small changes to the text prompt usually result in entirely different output images. However, with SEGA a variety of changes to the image are enabled that can be controlled easily and intuitively, while staying true to the original image composition.
|
| 17 |
+
|
| 18 |
+
The abstract from the paper is:
|
| 19 |
+
|
| 20 |
+
*Text-to-image diffusion models have recently received a lot of interest for their astonishing ability to produce high-fidelity images from text only. However, achieving one-shot generation that aligns with the user's intent is nearly impossible, yet small changes to the input prompt often result in very different images. This leaves the user with little semantic control. To put the user in control, we show how to interact with the diffusion process to flexibly steer it along semantic directions. This semantic guidance (SEGA) generalizes to any generative architecture using classifier-free guidance. More importantly, it allows for subtle and extensive edits, changes in composition and style, as well as optimizing the overall artistic conception. We demonstrate SEGA's effectiveness on both latent and pixel-based diffusion models such as Stable Diffusion, Paella, and DeepFloyd-IF using a variety of tasks, thus providing strong evidence for its versatility, flexibility, and improvements over existing methods.*
|
| 21 |
+
|
| 22 |
+
<Tip>
|
| 23 |
+
|
| 24 |
+
Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines.
|
| 25 |
+
|
| 26 |
+
</Tip>
|
| 27 |
+
|
| 28 |
+
## SemanticStableDiffusionPipeline
|
| 29 |
+
[[autodoc]] SemanticStableDiffusionPipeline
|
| 30 |
+
- all
|
| 31 |
+
- __call__
|
| 32 |
+
|
| 33 |
+
## SemanticStableDiffusionPipelineOutput
|
| 34 |
+
[[autodoc]] pipelines.semantic_stable_diffusion.pipeline_output.SemanticStableDiffusionPipelineOutput
|
| 35 |
+
- all
|
tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/shap_e.md
ADDED
|
@@ -0,0 +1,37 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 3 |
+
the License. You may obtain a copy of the License at
|
| 4 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 5 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 6 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 7 |
+
specific language governing permissions and limitations under the License.
|
| 8 |
+
-->
|
| 9 |
+
|
| 10 |
+
# Shap-E
|
| 11 |
+
|
| 12 |
+
The Shap-E model was proposed in [Shap-E: Generating Conditional 3D Implicit Functions](https://huggingface.co/papers/2305.02463) by Alex Nichol and Heewoo Jun from [OpenAI](https://github.com/openai).
|
| 13 |
+
|
| 14 |
+
The abstract from the paper is:
|
| 15 |
+
|
| 16 |
+
*We present Shap-E, a conditional generative model for 3D assets. Unlike recent work on 3D generative models which produce a single output representation, Shap-E directly generates the parameters of implicit functions that can be rendered as both textured meshes and neural radiance fields. We train Shap-E in two stages: first, we train an encoder that deterministically maps 3D assets into the parameters of an implicit function; second, we train a conditional diffusion model on outputs of the encoder. When trained on a large dataset of paired 3D and text data, our resulting models are capable of generating complex and diverse 3D assets in a matter of seconds. When compared to Point-E, an explicit generative model over point clouds, Shap-E converges faster and reaches comparable or better sample quality despite modeling a higher-dimensional, multi-representation output space.*
|
| 17 |
+
|
| 18 |
+
The original codebase can be found at [openai/shap-e](https://github.com/openai/shap-e).
|
| 19 |
+
|
| 20 |
+
<Tip>
|
| 21 |
+
|
| 22 |
+
See the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines.
|
| 23 |
+
|
| 24 |
+
</Tip>
|
| 25 |
+
|
| 26 |
+
## ShapEPipeline
|
| 27 |
+
[[autodoc]] ShapEPipeline
|
| 28 |
+
- all
|
| 29 |
+
- __call__
|
| 30 |
+
|
| 31 |
+
## ShapEImg2ImgPipeline
|
| 32 |
+
[[autodoc]] ShapEImg2ImgPipeline
|
| 33 |
+
- all
|
| 34 |
+
- __call__
|
| 35 |
+
|
| 36 |
+
## ShapEPipelineOutput
|
| 37 |
+
[[autodoc]] pipelines.shap_e.pipeline_shap_e.ShapEPipelineOutput
|
tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/stable_audio.md
ADDED
|
@@ -0,0 +1,93 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Stable Audio
|
| 14 |
+
|
| 15 |
+
Stable Audio was proposed in [Stable Audio Open](https://huggingface.co/papers/2407.14358) by Zach Evans et al. . it takes a text prompt as input and predicts the corresponding sound or music sample.
|
| 16 |
+
|
| 17 |
+
Stable Audio Open generates variable-length (up to 47s) stereo audio at 44.1kHz from text prompts. It comprises three components: an autoencoder that compresses waveforms into a manageable sequence length, a T5-based text embedding for text conditioning, and a transformer-based diffusion (DiT) model that operates in the latent space of the autoencoder.
|
| 18 |
+
|
| 19 |
+
Stable Audio is trained on a corpus of around 48k audio recordings, where around 47k are from Freesound and the rest are from the Free Music Archive (FMA). All audio files are licensed under CC0, CC BY, or CC Sampling+. This data is used to train the autoencoder and the DiT.
|
| 20 |
+
|
| 21 |
+
The abstract of the paper is the following:
|
| 22 |
+
*Open generative models are vitally important for the community, allowing for fine-tunes and serving as baselines when presenting new models. However, most current text-to-audio models are private and not accessible for artists and researchers to build upon. Here we describe the architecture and training process of a new open-weights text-to-audio model trained with Creative Commons data. Our evaluation shows that the model's performance is competitive with the state-of-the-art across various metrics. Notably, the reported FDopenl3 results (measuring the realism of the generations) showcase its potential for high-quality stereo sound synthesis at 44.1kHz.*
|
| 23 |
+
|
| 24 |
+
This pipeline was contributed by [Yoach Lacombe](https://huggingface.co/ylacombe). The original codebase can be found at [Stability-AI/stable-audio-tools](https://github.com/Stability-AI/stable-audio-tools).
|
| 25 |
+
|
| 26 |
+
## Tips
|
| 27 |
+
|
| 28 |
+
When constructing a prompt, keep in mind:
|
| 29 |
+
|
| 30 |
+
* Descriptive prompt inputs work best; use adjectives to describe the sound (for example, "high quality" or "clear") and make the prompt context specific where possible (e.g. "melodic techno with a fast beat and synths" works better than "techno").
|
| 31 |
+
* Using a *negative prompt* can significantly improve the quality of the generated audio. Try using a negative prompt of "low quality, average quality".
|
| 32 |
+
|
| 33 |
+
During inference:
|
| 34 |
+
|
| 35 |
+
* The _quality_ of the generated audio sample can be controlled by the `num_inference_steps` argument; higher steps give higher quality audio at the expense of slower inference.
|
| 36 |
+
* Multiple waveforms can be generated in one go: set `num_waveforms_per_prompt` to a value greater than 1 to enable. Automatic scoring will be performed between the generated waveforms and prompt text, and the audios ranked from best to worst accordingly.
|
| 37 |
+
|
| 38 |
+
## Quantization
|
| 39 |
+
|
| 40 |
+
Quantization helps reduce the memory requirements of very large models by storing model weights in a lower precision data type. However, quantization may have varying impact on video quality depending on the video model.
|
| 41 |
+
|
| 42 |
+
Refer to the [Quantization](../../quantization/overview) overview to learn more about supported quantization backends and selecting a quantization backend that supports your use case. The example below demonstrates how to load a quantized [`StableAudioPipeline`] for inference with bitsandbytes.
|
| 43 |
+
|
| 44 |
+
```py
|
| 45 |
+
import torch
|
| 46 |
+
from diffusers import BitsAndBytesConfig as DiffusersBitsAndBytesConfig, StableAudioDiTModel, StableAudioPipeline
|
| 47 |
+
from diffusers.utils import export_to_video
|
| 48 |
+
from transformers import BitsAndBytesConfig as BitsAndBytesConfig, T5EncoderModel
|
| 49 |
+
|
| 50 |
+
quant_config = BitsAndBytesConfig(load_in_8bit=True)
|
| 51 |
+
text_encoder_8bit = T5EncoderModel.from_pretrained(
|
| 52 |
+
"stabilityai/stable-audio-open-1.0",
|
| 53 |
+
subfolder="text_encoder",
|
| 54 |
+
quantization_config=quant_config,
|
| 55 |
+
torch_dtype=torch.float16,
|
| 56 |
+
)
|
| 57 |
+
|
| 58 |
+
quant_config = DiffusersBitsAndBytesConfig(load_in_8bit=True)
|
| 59 |
+
transformer_8bit = StableAudioDiTModel.from_pretrained(
|
| 60 |
+
"stabilityai/stable-audio-open-1.0",
|
| 61 |
+
subfolder="transformer",
|
| 62 |
+
quantization_config=quant_config,
|
| 63 |
+
torch_dtype=torch.float16,
|
| 64 |
+
)
|
| 65 |
+
|
| 66 |
+
pipeline = StableAudioPipeline.from_pretrained(
|
| 67 |
+
"stabilityai/stable-audio-open-1.0",
|
| 68 |
+
text_encoder=text_encoder_8bit,
|
| 69 |
+
transformer=transformer_8bit,
|
| 70 |
+
torch_dtype=torch.float16,
|
| 71 |
+
device_map="balanced",
|
| 72 |
+
)
|
| 73 |
+
|
| 74 |
+
prompt = "The sound of a hammer hitting a wooden surface."
|
| 75 |
+
negative_prompt = "Low quality."
|
| 76 |
+
audio = pipeline(
|
| 77 |
+
prompt,
|
| 78 |
+
negative_prompt=negative_prompt,
|
| 79 |
+
num_inference_steps=200,
|
| 80 |
+
audio_end_in_s=10.0,
|
| 81 |
+
num_waveforms_per_prompt=3,
|
| 82 |
+
generator=generator,
|
| 83 |
+
).audios
|
| 84 |
+
|
| 85 |
+
output = audio[0].T.float().cpu().numpy()
|
| 86 |
+
sf.write("hammer.wav", output, pipeline.vae.sampling_rate)
|
| 87 |
+
```
|
| 88 |
+
|
| 89 |
+
|
| 90 |
+
## StableAudioPipeline
|
| 91 |
+
[[autodoc]] StableAudioPipeline
|
| 92 |
+
- all
|
| 93 |
+
- __call__
|
tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/stable_cascade.md
ADDED
|
@@ -0,0 +1,229 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Stable Cascade
|
| 14 |
+
|
| 15 |
+
This model is built upon the [Würstchen](https://openreview.net/forum?id=gU58d5QeGv) architecture and its main
|
| 16 |
+
difference to other models like Stable Diffusion is that it is working at a much smaller latent space. Why is this
|
| 17 |
+
important? The smaller the latent space, the **faster** you can run inference and the **cheaper** the training becomes.
|
| 18 |
+
How small is the latent space? Stable Diffusion uses a compression factor of 8, resulting in a 1024x1024 image being
|
| 19 |
+
encoded to 128x128. Stable Cascade achieves a compression factor of 42, meaning that it is possible to encode a
|
| 20 |
+
1024x1024 image to 24x24, while maintaining crisp reconstructions. The text-conditional model is then trained in the
|
| 21 |
+
highly compressed latent space. Previous versions of this architecture, achieved a 16x cost reduction over Stable
|
| 22 |
+
Diffusion 1.5.
|
| 23 |
+
|
| 24 |
+
Therefore, this kind of model is well suited for usages where efficiency is important. Furthermore, all known extensions
|
| 25 |
+
like finetuning, LoRA, ControlNet, IP-Adapter, LCM etc. are possible with this method as well.
|
| 26 |
+
|
| 27 |
+
The original codebase can be found at [Stability-AI/StableCascade](https://github.com/Stability-AI/StableCascade).
|
| 28 |
+
|
| 29 |
+
## Model Overview
|
| 30 |
+
Stable Cascade consists of three models: Stage A, Stage B and Stage C, representing a cascade to generate images,
|
| 31 |
+
hence the name "Stable Cascade".
|
| 32 |
+
|
| 33 |
+
Stage A & B are used to compress images, similar to what the job of the VAE is in Stable Diffusion.
|
| 34 |
+
However, with this setup, a much higher compression of images can be achieved. While the Stable Diffusion models use a
|
| 35 |
+
spatial compression factor of 8, encoding an image with resolution of 1024 x 1024 to 128 x 128, Stable Cascade achieves
|
| 36 |
+
a compression factor of 42. This encodes a 1024 x 1024 image to 24 x 24, while being able to accurately decode the
|
| 37 |
+
image. This comes with the great benefit of cheaper training and inference. Furthermore, Stage C is responsible
|
| 38 |
+
for generating the small 24 x 24 latents given a text prompt.
|
| 39 |
+
|
| 40 |
+
The Stage C model operates on the small 24 x 24 latents and denoises the latents conditioned on text prompts. The model is also the largest component in the Cascade pipeline and is meant to be used with the `StableCascadePriorPipeline`
|
| 41 |
+
|
| 42 |
+
The Stage B and Stage A models are used with the `StableCascadeDecoderPipeline` and are responsible for generating the final image given the small 24 x 24 latents.
|
| 43 |
+
|
| 44 |
+
<Tip warning={true}>
|
| 45 |
+
|
| 46 |
+
There are some restrictions on data types that can be used with the Stable Cascade models. The official checkpoints for the `StableCascadePriorPipeline` do not support the `torch.float16` data type. Please use `torch.bfloat16` instead.
|
| 47 |
+
|
| 48 |
+
In order to use the `torch.bfloat16` data type with the `StableCascadeDecoderPipeline` you need to have PyTorch 2.2.0 or higher installed. This also means that using the `StableCascadeCombinedPipeline` with `torch.bfloat16` requires PyTorch 2.2.0 or higher, since it calls the `StableCascadeDecoderPipeline` internally.
|
| 49 |
+
|
| 50 |
+
If it is not possible to install PyTorch 2.2.0 or higher in your environment, the `StableCascadeDecoderPipeline` can be used on its own with the `torch.float16` data type. You can download the full precision or `bf16` variant weights for the pipeline and cast the weights to `torch.float16`.
|
| 51 |
+
|
| 52 |
+
</Tip>
|
| 53 |
+
|
| 54 |
+
## Usage example
|
| 55 |
+
|
| 56 |
+
```python
|
| 57 |
+
import torch
|
| 58 |
+
from diffusers import StableCascadeDecoderPipeline, StableCascadePriorPipeline
|
| 59 |
+
|
| 60 |
+
prompt = "an image of a shiba inu, donning a spacesuit and helmet"
|
| 61 |
+
negative_prompt = ""
|
| 62 |
+
|
| 63 |
+
prior = StableCascadePriorPipeline.from_pretrained("stabilityai/stable-cascade-prior", variant="bf16", torch_dtype=torch.bfloat16)
|
| 64 |
+
decoder = StableCascadeDecoderPipeline.from_pretrained("stabilityai/stable-cascade", variant="bf16", torch_dtype=torch.float16)
|
| 65 |
+
|
| 66 |
+
prior.enable_model_cpu_offload()
|
| 67 |
+
prior_output = prior(
|
| 68 |
+
prompt=prompt,
|
| 69 |
+
height=1024,
|
| 70 |
+
width=1024,
|
| 71 |
+
negative_prompt=negative_prompt,
|
| 72 |
+
guidance_scale=4.0,
|
| 73 |
+
num_images_per_prompt=1,
|
| 74 |
+
num_inference_steps=20
|
| 75 |
+
)
|
| 76 |
+
|
| 77 |
+
decoder.enable_model_cpu_offload()
|
| 78 |
+
decoder_output = decoder(
|
| 79 |
+
image_embeddings=prior_output.image_embeddings.to(torch.float16),
|
| 80 |
+
prompt=prompt,
|
| 81 |
+
negative_prompt=negative_prompt,
|
| 82 |
+
guidance_scale=0.0,
|
| 83 |
+
output_type="pil",
|
| 84 |
+
num_inference_steps=10
|
| 85 |
+
).images[0]
|
| 86 |
+
decoder_output.save("cascade.png")
|
| 87 |
+
```
|
| 88 |
+
|
| 89 |
+
## Using the Lite Versions of the Stage B and Stage C models
|
| 90 |
+
|
| 91 |
+
```python
|
| 92 |
+
import torch
|
| 93 |
+
from diffusers import (
|
| 94 |
+
StableCascadeDecoderPipeline,
|
| 95 |
+
StableCascadePriorPipeline,
|
| 96 |
+
StableCascadeUNet,
|
| 97 |
+
)
|
| 98 |
+
|
| 99 |
+
prompt = "an image of a shiba inu, donning a spacesuit and helmet"
|
| 100 |
+
negative_prompt = ""
|
| 101 |
+
|
| 102 |
+
prior_unet = StableCascadeUNet.from_pretrained("stabilityai/stable-cascade-prior", subfolder="prior_lite")
|
| 103 |
+
decoder_unet = StableCascadeUNet.from_pretrained("stabilityai/stable-cascade", subfolder="decoder_lite")
|
| 104 |
+
|
| 105 |
+
prior = StableCascadePriorPipeline.from_pretrained("stabilityai/stable-cascade-prior", prior=prior_unet)
|
| 106 |
+
decoder = StableCascadeDecoderPipeline.from_pretrained("stabilityai/stable-cascade", decoder=decoder_unet)
|
| 107 |
+
|
| 108 |
+
prior.enable_model_cpu_offload()
|
| 109 |
+
prior_output = prior(
|
| 110 |
+
prompt=prompt,
|
| 111 |
+
height=1024,
|
| 112 |
+
width=1024,
|
| 113 |
+
negative_prompt=negative_prompt,
|
| 114 |
+
guidance_scale=4.0,
|
| 115 |
+
num_images_per_prompt=1,
|
| 116 |
+
num_inference_steps=20
|
| 117 |
+
)
|
| 118 |
+
|
| 119 |
+
decoder.enable_model_cpu_offload()
|
| 120 |
+
decoder_output = decoder(
|
| 121 |
+
image_embeddings=prior_output.image_embeddings,
|
| 122 |
+
prompt=prompt,
|
| 123 |
+
negative_prompt=negative_prompt,
|
| 124 |
+
guidance_scale=0.0,
|
| 125 |
+
output_type="pil",
|
| 126 |
+
num_inference_steps=10
|
| 127 |
+
).images[0]
|
| 128 |
+
decoder_output.save("cascade.png")
|
| 129 |
+
```
|
| 130 |
+
|
| 131 |
+
## Loading original checkpoints with `from_single_file`
|
| 132 |
+
|
| 133 |
+
Loading the original format checkpoints is supported via `from_single_file` method in the StableCascadeUNet.
|
| 134 |
+
|
| 135 |
+
```python
|
| 136 |
+
import torch
|
| 137 |
+
from diffusers import (
|
| 138 |
+
StableCascadeDecoderPipeline,
|
| 139 |
+
StableCascadePriorPipeline,
|
| 140 |
+
StableCascadeUNet,
|
| 141 |
+
)
|
| 142 |
+
|
| 143 |
+
prompt = "an image of a shiba inu, donning a spacesuit and helmet"
|
| 144 |
+
negative_prompt = ""
|
| 145 |
+
|
| 146 |
+
prior_unet = StableCascadeUNet.from_single_file(
|
| 147 |
+
"https://huggingface.co/stabilityai/stable-cascade/resolve/main/stage_c_bf16.safetensors",
|
| 148 |
+
torch_dtype=torch.bfloat16
|
| 149 |
+
)
|
| 150 |
+
decoder_unet = StableCascadeUNet.from_single_file(
|
| 151 |
+
"https://huggingface.co/stabilityai/stable-cascade/blob/main/stage_b_bf16.safetensors",
|
| 152 |
+
torch_dtype=torch.bfloat16
|
| 153 |
+
)
|
| 154 |
+
|
| 155 |
+
prior = StableCascadePriorPipeline.from_pretrained("stabilityai/stable-cascade-prior", prior=prior_unet, torch_dtype=torch.bfloat16)
|
| 156 |
+
decoder = StableCascadeDecoderPipeline.from_pretrained("stabilityai/stable-cascade", decoder=decoder_unet, torch_dtype=torch.bfloat16)
|
| 157 |
+
|
| 158 |
+
prior.enable_model_cpu_offload()
|
| 159 |
+
prior_output = prior(
|
| 160 |
+
prompt=prompt,
|
| 161 |
+
height=1024,
|
| 162 |
+
width=1024,
|
| 163 |
+
negative_prompt=negative_prompt,
|
| 164 |
+
guidance_scale=4.0,
|
| 165 |
+
num_images_per_prompt=1,
|
| 166 |
+
num_inference_steps=20
|
| 167 |
+
)
|
| 168 |
+
|
| 169 |
+
decoder.enable_model_cpu_offload()
|
| 170 |
+
decoder_output = decoder(
|
| 171 |
+
image_embeddings=prior_output.image_embeddings,
|
| 172 |
+
prompt=prompt,
|
| 173 |
+
negative_prompt=negative_prompt,
|
| 174 |
+
guidance_scale=0.0,
|
| 175 |
+
output_type="pil",
|
| 176 |
+
num_inference_steps=10
|
| 177 |
+
).images[0]
|
| 178 |
+
decoder_output.save("cascade-single-file.png")
|
| 179 |
+
```
|
| 180 |
+
|
| 181 |
+
## Uses
|
| 182 |
+
|
| 183 |
+
### Direct Use
|
| 184 |
+
|
| 185 |
+
The model is intended for research purposes for now. Possible research areas and tasks include
|
| 186 |
+
|
| 187 |
+
- Research on generative models.
|
| 188 |
+
- Safe deployment of models which have the potential to generate harmful content.
|
| 189 |
+
- Probing and understanding the limitations and biases of generative models.
|
| 190 |
+
- Generation of artworks and use in design and other artistic processes.
|
| 191 |
+
- Applications in educational or creative tools.
|
| 192 |
+
|
| 193 |
+
Excluded uses are described below.
|
| 194 |
+
|
| 195 |
+
### Out-of-Scope Use
|
| 196 |
+
|
| 197 |
+
The model was not trained to be factual or true representations of people or events,
|
| 198 |
+
and therefore using the model to generate such content is out-of-scope for the abilities of this model.
|
| 199 |
+
The model should not be used in any way that violates Stability AI's [Acceptable Use Policy](https://stability.ai/use-policy).
|
| 200 |
+
|
| 201 |
+
## Limitations and Bias
|
| 202 |
+
|
| 203 |
+
### Limitations
|
| 204 |
+
- Faces and people in general may not be generated properly.
|
| 205 |
+
- The autoencoding part of the model is lossy.
|
| 206 |
+
|
| 207 |
+
|
| 208 |
+
## StableCascadeCombinedPipeline
|
| 209 |
+
|
| 210 |
+
[[autodoc]] StableCascadeCombinedPipeline
|
| 211 |
+
- all
|
| 212 |
+
- __call__
|
| 213 |
+
|
| 214 |
+
## StableCascadePriorPipeline
|
| 215 |
+
|
| 216 |
+
[[autodoc]] StableCascadePriorPipeline
|
| 217 |
+
- all
|
| 218 |
+
- __call__
|
| 219 |
+
|
| 220 |
+
## StableCascadePriorPipelineOutput
|
| 221 |
+
|
| 222 |
+
[[autodoc]] pipelines.stable_cascade.pipeline_stable_cascade_prior.StableCascadePriorPipelineOutput
|
| 223 |
+
|
| 224 |
+
## StableCascadeDecoderPipeline
|
| 225 |
+
|
| 226 |
+
[[autodoc]] StableCascadeDecoderPipeline
|
| 227 |
+
- all
|
| 228 |
+
- __call__
|
| 229 |
+
|
tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/stable_diffusion/adapter.md
ADDED
|
@@ -0,0 +1,47 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# T2I-Adapter
|
| 14 |
+
|
| 15 |
+
[T2I-Adapter: Learning Adapters to Dig out More Controllable Ability for Text-to-Image Diffusion Models](https://huggingface.co/papers/2302.08453) by Chong Mou, Xintao Wang, Liangbin Xie, Jian Zhang, Zhongang Qi, Ying Shan, Xiaohu Qie.
|
| 16 |
+
|
| 17 |
+
Using the pretrained models we can provide control images (for example, a depth map) to control Stable Diffusion text-to-image generation so that it follows the structure of the depth image and fills in the details.
|
| 18 |
+
|
| 19 |
+
The abstract of the paper is the following:
|
| 20 |
+
|
| 21 |
+
*The incredible generative ability of large-scale text-to-image (T2I) models has demonstrated strong power of learning complex structures and meaningful semantics. However, relying solely on text prompts cannot fully take advantage of the knowledge learned by the model, especially when flexible and accurate controlling (e.g., color and structure) is needed. In this paper, we aim to ``dig out" the capabilities that T2I models have implicitly learned, and then explicitly use them to control the generation more granularly. Specifically, we propose to learn simple and lightweight T2I-Adapters to align internal knowledge in T2I models with external control signals, while freezing the original large T2I models. In this way, we can train various adapters according to different conditions, achieving rich control and editing effects in the color and structure of the generation results. Further, the proposed T2I-Adapters have attractive properties of practical value, such as composability and generalization ability. Extensive experiments demonstrate that our T2I-Adapter has promising generation quality and a wide range of applications.*
|
| 22 |
+
|
| 23 |
+
This model was contributed by the community contributor [HimariO](https://github.com/HimariO) ❤️ .
|
| 24 |
+
|
| 25 |
+
## StableDiffusionAdapterPipeline
|
| 26 |
+
|
| 27 |
+
[[autodoc]] StableDiffusionAdapterPipeline
|
| 28 |
+
- all
|
| 29 |
+
- __call__
|
| 30 |
+
- enable_attention_slicing
|
| 31 |
+
- disable_attention_slicing
|
| 32 |
+
- enable_vae_slicing
|
| 33 |
+
- disable_vae_slicing
|
| 34 |
+
- enable_xformers_memory_efficient_attention
|
| 35 |
+
- disable_xformers_memory_efficient_attention
|
| 36 |
+
|
| 37 |
+
## StableDiffusionXLAdapterPipeline
|
| 38 |
+
|
| 39 |
+
[[autodoc]] StableDiffusionXLAdapterPipeline
|
| 40 |
+
- all
|
| 41 |
+
- __call__
|
| 42 |
+
- enable_attention_slicing
|
| 43 |
+
- disable_attention_slicing
|
| 44 |
+
- enable_vae_slicing
|
| 45 |
+
- disable_vae_slicing
|
| 46 |
+
- enable_xformers_memory_efficient_attention
|
| 47 |
+
- disable_xformers_memory_efficient_attention
|
tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/stable_diffusion/depth2img.md
ADDED
|
@@ -0,0 +1,44 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Depth-to-image
|
| 14 |
+
|
| 15 |
+
<div class="flex flex-wrap space-x-1">
|
| 16 |
+
<img alt="LoRA" src="https://img.shields.io/badge/LoRA-d8b4fe?style=flat"/>
|
| 17 |
+
</div>
|
| 18 |
+
|
| 19 |
+
The Stable Diffusion model can also infer depth based on an image using [MiDaS](https://github.com/isl-org/MiDaS). This allows you to pass a text prompt and an initial image to condition the generation of new images as well as a `depth_map` to preserve the image structure.
|
| 20 |
+
|
| 21 |
+
<Tip>
|
| 22 |
+
|
| 23 |
+
Make sure to check out the Stable Diffusion [Tips](overview#tips) section to learn how to explore the tradeoff between scheduler speed and quality, and how to reuse pipeline components efficiently!
|
| 24 |
+
|
| 25 |
+
If you're interested in using one of the official checkpoints for a task, explore the [CompVis](https://huggingface.co/CompVis), [Runway](https://huggingface.co/runwayml), and [Stability AI](https://huggingface.co/stabilityai) Hub organizations!
|
| 26 |
+
|
| 27 |
+
</Tip>
|
| 28 |
+
|
| 29 |
+
## StableDiffusionDepth2ImgPipeline
|
| 30 |
+
|
| 31 |
+
[[autodoc]] StableDiffusionDepth2ImgPipeline
|
| 32 |
+
- all
|
| 33 |
+
- __call__
|
| 34 |
+
- enable_attention_slicing
|
| 35 |
+
- disable_attention_slicing
|
| 36 |
+
- enable_xformers_memory_efficient_attention
|
| 37 |
+
- disable_xformers_memory_efficient_attention
|
| 38 |
+
- load_textual_inversion
|
| 39 |
+
- load_lora_weights
|
| 40 |
+
- save_lora_weights
|
| 41 |
+
|
| 42 |
+
## StableDiffusionPipelineOutput
|
| 43 |
+
|
| 44 |
+
[[autodoc]] pipelines.stable_diffusion.StableDiffusionPipelineOutput
|
tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/stable_diffusion/gligen.md
ADDED
|
@@ -0,0 +1,59 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The GLIGEN Authors and The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# GLIGEN (Grounded Language-to-Image Generation)
|
| 14 |
+
|
| 15 |
+
The GLIGEN model was created by researchers and engineers from [University of Wisconsin-Madison, Columbia University, and Microsoft](https://github.com/gligen/GLIGEN). The [`StableDiffusionGLIGENPipeline`] and [`StableDiffusionGLIGENTextImagePipeline`] can generate photorealistic images conditioned on grounding inputs. Along with text and bounding boxes with [`StableDiffusionGLIGENPipeline`], if input images are given, [`StableDiffusionGLIGENTextImagePipeline`] can insert objects described by text at the region defined by bounding boxes. Otherwise, it'll generate an image described by the caption/prompt and insert objects described by text at the region defined by bounding boxes. It's trained on COCO2014D and COCO2014CD datasets, and the model uses a frozen CLIP ViT-L/14 text encoder to condition itself on grounding inputs.
|
| 16 |
+
|
| 17 |
+
The abstract from the [paper](https://huggingface.co/papers/2301.07093) is:
|
| 18 |
+
|
| 19 |
+
*Large-scale text-to-image diffusion models have made amazing advances. However, the status quo is to use text input alone, which can impede controllability. In this work, we propose GLIGEN, Grounded-Language-to-Image Generation, a novel approach that builds upon and extends the functionality of existing pre-trained text-to-image diffusion models by enabling them to also be conditioned on grounding inputs. To preserve the vast concept knowledge of the pre-trained model, we freeze all of its weights and inject the grounding information into new trainable layers via a gated mechanism. Our model achieves open-world grounded text2img generation with caption and bounding box condition inputs, and the grounding ability generalizes well to novel spatial configurations and concepts. GLIGEN’s zeroshot performance on COCO and LVIS outperforms existing supervised layout-to-image baselines by a large margin.*
|
| 20 |
+
|
| 21 |
+
<Tip>
|
| 22 |
+
|
| 23 |
+
Make sure to check out the Stable Diffusion [Tips](https://huggingface.co/docs/diffusers/en/api/pipelines/stable_diffusion/overview#tips) section to learn how to explore the tradeoff between scheduler speed and quality and how to reuse pipeline components efficiently!
|
| 24 |
+
|
| 25 |
+
If you want to use one of the official checkpoints for a task, explore the [gligen](https://huggingface.co/gligen) Hub organizations!
|
| 26 |
+
|
| 27 |
+
</Tip>
|
| 28 |
+
|
| 29 |
+
[`StableDiffusionGLIGENPipeline`] was contributed by [Nikhil Gajendrakumar](https://github.com/nikhil-masterful) and [`StableDiffusionGLIGENTextImagePipeline`] was contributed by [Nguyễn Công Tú Anh](https://github.com/tuanh123789).
|
| 30 |
+
|
| 31 |
+
## StableDiffusionGLIGENPipeline
|
| 32 |
+
|
| 33 |
+
[[autodoc]] StableDiffusionGLIGENPipeline
|
| 34 |
+
- all
|
| 35 |
+
- __call__
|
| 36 |
+
- enable_vae_slicing
|
| 37 |
+
- disable_vae_slicing
|
| 38 |
+
- enable_vae_tiling
|
| 39 |
+
- disable_vae_tiling
|
| 40 |
+
- enable_model_cpu_offload
|
| 41 |
+
- prepare_latents
|
| 42 |
+
- enable_fuser
|
| 43 |
+
|
| 44 |
+
## StableDiffusionGLIGENTextImagePipeline
|
| 45 |
+
|
| 46 |
+
[[autodoc]] StableDiffusionGLIGENTextImagePipeline
|
| 47 |
+
- all
|
| 48 |
+
- __call__
|
| 49 |
+
- enable_vae_slicing
|
| 50 |
+
- disable_vae_slicing
|
| 51 |
+
- enable_vae_tiling
|
| 52 |
+
- disable_vae_tiling
|
| 53 |
+
- enable_model_cpu_offload
|
| 54 |
+
- prepare_latents
|
| 55 |
+
- enable_fuser
|
| 56 |
+
|
| 57 |
+
## StableDiffusionPipelineOutput
|
| 58 |
+
|
| 59 |
+
[[autodoc]] pipelines.stable_diffusion.StableDiffusionPipelineOutput
|
tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/stable_diffusion/image_variation.md
ADDED
|
@@ -0,0 +1,37 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Image variation
|
| 14 |
+
|
| 15 |
+
The Stable Diffusion model can also generate variations from an input image. It uses a fine-tuned version of a Stable Diffusion model by [Justin Pinkney](https://www.justinpinkney.com/) from [Lambda](https://lambdalabs.com/).
|
| 16 |
+
|
| 17 |
+
The original codebase can be found at [LambdaLabsML/lambda-diffusers](https://github.com/LambdaLabsML/lambda-diffusers#stable-diffusion-image-variations) and additional official checkpoints for image variation can be found at [lambdalabs/sd-image-variations-diffusers](https://huggingface.co/lambdalabs/sd-image-variations-diffusers).
|
| 18 |
+
|
| 19 |
+
<Tip>
|
| 20 |
+
|
| 21 |
+
Make sure to check out the Stable Diffusion [Tips](./overview#tips) section to learn how to explore the tradeoff between scheduler speed and quality, and how to reuse pipeline components efficiently!
|
| 22 |
+
|
| 23 |
+
</Tip>
|
| 24 |
+
|
| 25 |
+
## StableDiffusionImageVariationPipeline
|
| 26 |
+
|
| 27 |
+
[[autodoc]] StableDiffusionImageVariationPipeline
|
| 28 |
+
- all
|
| 29 |
+
- __call__
|
| 30 |
+
- enable_attention_slicing
|
| 31 |
+
- disable_attention_slicing
|
| 32 |
+
- enable_xformers_memory_efficient_attention
|
| 33 |
+
- disable_xformers_memory_efficient_attention
|
| 34 |
+
|
| 35 |
+
## StableDiffusionPipelineOutput
|
| 36 |
+
|
| 37 |
+
[[autodoc]] pipelines.stable_diffusion.StableDiffusionPipelineOutput
|
tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/stable_diffusion/img2img.md
ADDED
|
@@ -0,0 +1,59 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Image-to-image
|
| 14 |
+
|
| 15 |
+
<div class="flex flex-wrap space-x-1">
|
| 16 |
+
<img alt="LoRA" src="https://img.shields.io/badge/LoRA-d8b4fe?style=flat"/>
|
| 17 |
+
</div>
|
| 18 |
+
|
| 19 |
+
The Stable Diffusion model can also be applied to image-to-image generation by passing a text prompt and an initial image to condition the generation of new images.
|
| 20 |
+
|
| 21 |
+
The [`StableDiffusionImg2ImgPipeline`] uses the diffusion-denoising mechanism proposed in [SDEdit: Guided Image Synthesis and Editing with Stochastic Differential Equations](https://huggingface.co/papers/2108.01073) by Chenlin Meng, Yutong He, Yang Song, Jiaming Song, Jiajun Wu, Jun-Yan Zhu, Stefano Ermon.
|
| 22 |
+
|
| 23 |
+
The abstract from the paper is:
|
| 24 |
+
|
| 25 |
+
*Guided image synthesis enables everyday users to create and edit photo-realistic images with minimum effort. The key challenge is balancing faithfulness to the user input (e.g., hand-drawn colored strokes) and realism of the synthesized image. Existing GAN-based methods attempt to achieve such balance using either conditional GANs or GAN inversions, which are challenging and often require additional training data or loss functions for individual applications. To address these issues, we introduce a new image synthesis and editing method, Stochastic Differential Editing (SDEdit), based on a diffusion model generative prior, which synthesizes realistic images by iteratively denoising through a stochastic differential equation (SDE). Given an input image with user guide of any type, SDEdit first adds noise to the input, then subsequently denoises the resulting image through the SDE prior to increase its realism. SDEdit does not require task-specific training or inversions and can naturally achieve the balance between realism and faithfulness. SDEdit significantly outperforms state-of-the-art GAN-based methods by up to 98.09% on realism and 91.72% on overall satisfaction scores, according to a human perception study, on multiple tasks, including stroke-based image synthesis and editing as well as image compositing.*
|
| 26 |
+
|
| 27 |
+
<Tip>
|
| 28 |
+
|
| 29 |
+
Make sure to check out the Stable Diffusion [Tips](overview#tips) section to learn how to explore the tradeoff between scheduler speed and quality, and how to reuse pipeline components efficiently!
|
| 30 |
+
|
| 31 |
+
</Tip>
|
| 32 |
+
|
| 33 |
+
## StableDiffusionImg2ImgPipeline
|
| 34 |
+
|
| 35 |
+
[[autodoc]] StableDiffusionImg2ImgPipeline
|
| 36 |
+
- all
|
| 37 |
+
- __call__
|
| 38 |
+
- enable_attention_slicing
|
| 39 |
+
- disable_attention_slicing
|
| 40 |
+
- enable_xformers_memory_efficient_attention
|
| 41 |
+
- disable_xformers_memory_efficient_attention
|
| 42 |
+
- load_textual_inversion
|
| 43 |
+
- from_single_file
|
| 44 |
+
- load_lora_weights
|
| 45 |
+
- save_lora_weights
|
| 46 |
+
|
| 47 |
+
## StableDiffusionPipelineOutput
|
| 48 |
+
|
| 49 |
+
[[autodoc]] pipelines.stable_diffusion.StableDiffusionPipelineOutput
|
| 50 |
+
|
| 51 |
+
## FlaxStableDiffusionImg2ImgPipeline
|
| 52 |
+
|
| 53 |
+
[[autodoc]] FlaxStableDiffusionImg2ImgPipeline
|
| 54 |
+
- all
|
| 55 |
+
- __call__
|
| 56 |
+
|
| 57 |
+
## FlaxStableDiffusionPipelineOutput
|
| 58 |
+
|
| 59 |
+
[[autodoc]] pipelines.stable_diffusion.FlaxStableDiffusionPipelineOutput
|
tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/stable_diffusion/inpaint.md
ADDED
|
@@ -0,0 +1,61 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Inpainting
|
| 14 |
+
|
| 15 |
+
<div class="flex flex-wrap space-x-1">
|
| 16 |
+
<img alt="LoRA" src="https://img.shields.io/badge/LoRA-d8b4fe?style=flat"/>
|
| 17 |
+
</div>
|
| 18 |
+
|
| 19 |
+
The Stable Diffusion model can also be applied to inpainting which lets you edit specific parts of an image by providing a mask and a text prompt using Stable Diffusion.
|
| 20 |
+
|
| 21 |
+
## Tips
|
| 22 |
+
|
| 23 |
+
It is recommended to use this pipeline with checkpoints that have been specifically fine-tuned for inpainting, such
|
| 24 |
+
as [runwayml/stable-diffusion-inpainting](https://huggingface.co/runwayml/stable-diffusion-inpainting). Default
|
| 25 |
+
text-to-image Stable Diffusion checkpoints, such as
|
| 26 |
+
[stable-diffusion-v1-5/stable-diffusion-v1-5](https://huggingface.co/stable-diffusion-v1-5/stable-diffusion-v1-5) are also compatible but they might be less performant.
|
| 27 |
+
|
| 28 |
+
<Tip>
|
| 29 |
+
|
| 30 |
+
Make sure to check out the Stable Diffusion [Tips](overview#tips) section to learn how to explore the tradeoff between scheduler speed and quality, and how to reuse pipeline components efficiently!
|
| 31 |
+
|
| 32 |
+
If you're interested in using one of the official checkpoints for a task, explore the [CompVis](https://huggingface.co/CompVis), [Runway](https://huggingface.co/runwayml), and [Stability AI](https://huggingface.co/stabilityai) Hub organizations!
|
| 33 |
+
|
| 34 |
+
</Tip>
|
| 35 |
+
|
| 36 |
+
## StableDiffusionInpaintPipeline
|
| 37 |
+
|
| 38 |
+
[[autodoc]] StableDiffusionInpaintPipeline
|
| 39 |
+
- all
|
| 40 |
+
- __call__
|
| 41 |
+
- enable_attention_slicing
|
| 42 |
+
- disable_attention_slicing
|
| 43 |
+
- enable_xformers_memory_efficient_attention
|
| 44 |
+
- disable_xformers_memory_efficient_attention
|
| 45 |
+
- load_textual_inversion
|
| 46 |
+
- load_lora_weights
|
| 47 |
+
- save_lora_weights
|
| 48 |
+
|
| 49 |
+
## StableDiffusionPipelineOutput
|
| 50 |
+
|
| 51 |
+
[[autodoc]] pipelines.stable_diffusion.StableDiffusionPipelineOutput
|
| 52 |
+
|
| 53 |
+
## FlaxStableDiffusionInpaintPipeline
|
| 54 |
+
|
| 55 |
+
[[autodoc]] FlaxStableDiffusionInpaintPipeline
|
| 56 |
+
- all
|
| 57 |
+
- __call__
|
| 58 |
+
|
| 59 |
+
## FlaxStableDiffusionPipelineOutput
|
| 60 |
+
|
| 61 |
+
[[autodoc]] pipelines.stable_diffusion.FlaxStableDiffusionPipelineOutput
|
tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/stable_diffusion/k_diffusion.md
ADDED
|
@@ -0,0 +1,27 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# K-Diffusion
|
| 14 |
+
|
| 15 |
+
[k-diffusion](https://github.com/crowsonkb/k-diffusion) is a popular library created by [Katherine Crowson](https://github.com/crowsonkb/). We provide `StableDiffusionKDiffusionPipeline` and `StableDiffusionXLKDiffusionPipeline` that allow you to run Stable DIffusion with samplers from k-diffusion.
|
| 16 |
+
|
| 17 |
+
Note that most the samplers from k-diffusion are implemented in Diffusers and we recommend using existing schedulers. You can find a mapping between k-diffusion samplers and schedulers in Diffusers [here](https://huggingface.co/docs/diffusers/api/schedulers/overview)
|
| 18 |
+
|
| 19 |
+
|
| 20 |
+
## StableDiffusionKDiffusionPipeline
|
| 21 |
+
|
| 22 |
+
[[autodoc]] StableDiffusionKDiffusionPipeline
|
| 23 |
+
|
| 24 |
+
|
| 25 |
+
## StableDiffusionXLKDiffusionPipeline
|
| 26 |
+
|
| 27 |
+
[[autodoc]] StableDiffusionXLKDiffusionPipeline
|
tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/stable_diffusion/latent_upscale.md
ADDED
|
@@ -0,0 +1,38 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Latent upscaler
|
| 14 |
+
|
| 15 |
+
The Stable Diffusion latent upscaler model was created by [Katherine Crowson](https://github.com/crowsonkb/k-diffusion) in collaboration with [Stability AI](https://stability.ai/). It is used to enhance the output image resolution by a factor of 2 (see this demo [notebook](https://colab.research.google.com/drive/1o1qYJcFeywzCIdkfKJy7cTpgZTCM2EI4) for a demonstration of the original implementation).
|
| 16 |
+
|
| 17 |
+
<Tip>
|
| 18 |
+
|
| 19 |
+
Make sure to check out the Stable Diffusion [Tips](overview#tips) section to learn how to explore the tradeoff between scheduler speed and quality, and how to reuse pipeline components efficiently!
|
| 20 |
+
|
| 21 |
+
If you're interested in using one of the official checkpoints for a task, explore the [CompVis](https://huggingface.co/CompVis), [Runway](https://huggingface.co/runwayml), and [Stability AI](https://huggingface.co/stabilityai) Hub organizations!
|
| 22 |
+
|
| 23 |
+
</Tip>
|
| 24 |
+
|
| 25 |
+
## StableDiffusionLatentUpscalePipeline
|
| 26 |
+
|
| 27 |
+
[[autodoc]] StableDiffusionLatentUpscalePipeline
|
| 28 |
+
- all
|
| 29 |
+
- __call__
|
| 30 |
+
- enable_sequential_cpu_offload
|
| 31 |
+
- enable_attention_slicing
|
| 32 |
+
- disable_attention_slicing
|
| 33 |
+
- enable_xformers_memory_efficient_attention
|
| 34 |
+
- disable_xformers_memory_efficient_attention
|
| 35 |
+
|
| 36 |
+
## StableDiffusionPipelineOutput
|
| 37 |
+
|
| 38 |
+
[[autodoc]] pipelines.stable_diffusion.StableDiffusionPipelineOutput
|
tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/stable_diffusion/ldm3d_diffusion.md
ADDED
|
@@ -0,0 +1,59 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The Intel Labs Team Authors and HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Text-to-(RGB, depth)
|
| 14 |
+
|
| 15 |
+
<div class="flex flex-wrap space-x-1">
|
| 16 |
+
<img alt="LoRA" src="https://img.shields.io/badge/LoRA-d8b4fe?style=flat"/>
|
| 17 |
+
</div>
|
| 18 |
+
|
| 19 |
+
LDM3D was proposed in [LDM3D: Latent Diffusion Model for 3D](https://huggingface.co/papers/2305.10853) by Gabriela Ben Melech Stan, Diana Wofk, Scottie Fox, Alex Redden, Will Saxton, Jean Yu, Estelle Aflalo, Shao-Yen Tseng, Fabio Nonato, Matthias Muller, and Vasudev Lal. LDM3D generates an image and a depth map from a given text prompt unlike the existing text-to-image diffusion models such as [Stable Diffusion](./overview) which only generates an image. With almost the same number of parameters, LDM3D achieves to create a latent space that can compress both the RGB images and the depth maps.
|
| 20 |
+
|
| 21 |
+
Two checkpoints are available for use:
|
| 22 |
+
- [ldm3d-original](https://huggingface.co/Intel/ldm3d). The original checkpoint used in the [paper](https://huggingface.co/papers/2305.10853)
|
| 23 |
+
- [ldm3d-4c](https://huggingface.co/Intel/ldm3d-4c). The new version of LDM3D using 4 channels inputs instead of 6-channels inputs and finetuned on higher resolution images.
|
| 24 |
+
|
| 25 |
+
|
| 26 |
+
The abstract from the paper is:
|
| 27 |
+
|
| 28 |
+
*This research paper proposes a Latent Diffusion Model for 3D (LDM3D) that generates both image and depth map data from a given text prompt, allowing users to generate RGBD images from text prompts. The LDM3D model is fine-tuned on a dataset of tuples containing an RGB image, depth map and caption, and validated through extensive experiments. We also develop an application called DepthFusion, which uses the generated RGB images and depth maps to create immersive and interactive 360-degree-view experiences using TouchDesigner. This technology has the potential to transform a wide range of industries, from entertainment and gaming to architecture and design. Overall, this paper presents a significant contribution to the field of generative AI and computer vision, and showcases the potential of LDM3D and DepthFusion to revolutionize content creation and digital experiences. A short video summarizing the approach can be found at [this url](https://t.ly/tdi2).*
|
| 29 |
+
|
| 30 |
+
<Tip>
|
| 31 |
+
|
| 32 |
+
Make sure to check out the Stable Diffusion [Tips](overview#tips) section to learn how to explore the tradeoff between scheduler speed and quality, and how to reuse pipeline components efficiently!
|
| 33 |
+
|
| 34 |
+
</Tip>
|
| 35 |
+
|
| 36 |
+
## StableDiffusionLDM3DPipeline
|
| 37 |
+
|
| 38 |
+
[[autodoc]] pipelines.stable_diffusion_ldm3d.pipeline_stable_diffusion_ldm3d.StableDiffusionLDM3DPipeline
|
| 39 |
+
- all
|
| 40 |
+
- __call__
|
| 41 |
+
|
| 42 |
+
|
| 43 |
+
## LDM3DPipelineOutput
|
| 44 |
+
|
| 45 |
+
[[autodoc]] pipelines.stable_diffusion_ldm3d.pipeline_stable_diffusion_ldm3d.LDM3DPipelineOutput
|
| 46 |
+
- all
|
| 47 |
+
- __call__
|
| 48 |
+
|
| 49 |
+
# Upscaler
|
| 50 |
+
|
| 51 |
+
[LDM3D-VR](https://huggingface.co/papers/2311.03226) is an extended version of LDM3D.
|
| 52 |
+
|
| 53 |
+
The abstract from the paper is:
|
| 54 |
+
*Latent diffusion models have proven to be state-of-the-art in the creation and manipulation of visual outputs. However, as far as we know, the generation of depth maps jointly with RGB is still limited. We introduce LDM3D-VR, a suite of diffusion models targeting virtual reality development that includes LDM3D-pano and LDM3D-SR. These models enable the generation of panoramic RGBD based on textual prompts and the upscaling of low-resolution inputs to high-resolution RGBD, respectively. Our models are fine-tuned from existing pretrained models on datasets containing panoramic/high-resolution RGB images, depth maps and captions. Both models are evaluated in comparison to existing related methods*
|
| 55 |
+
|
| 56 |
+
Two checkpoints are available for use:
|
| 57 |
+
- [ldm3d-pano](https://huggingface.co/Intel/ldm3d-pano). This checkpoint enables the generation of panoramic images and requires the StableDiffusionLDM3DPipeline pipeline to be used.
|
| 58 |
+
- [ldm3d-sr](https://huggingface.co/Intel/ldm3d-sr). This checkpoint enables the upscaling of RGB and depth images. Can be used in cascade after the original LDM3D pipeline using the StableDiffusionUpscaleLDM3DPipeline from communauty pipeline.
|
| 59 |
+
|
tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/stable_diffusion/overview.md
ADDED
|
@@ -0,0 +1,216 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Stable Diffusion pipelines
|
| 14 |
+
|
| 15 |
+
<div class="flex flex-wrap space-x-1">
|
| 16 |
+
<img alt="LoRA" src="https://img.shields.io/badge/LoRA-d8b4fe?style=flat"/>
|
| 17 |
+
</div>
|
| 18 |
+
|
| 19 |
+
Stable Diffusion is a text-to-image latent diffusion model created by the researchers and engineers from [CompVis](https://github.com/CompVis), [Stability AI](https://stability.ai/) and [LAION](https://laion.ai/). Latent diffusion applies the diffusion process over a lower dimensional latent space to reduce memory and compute complexity. This specific type of diffusion model was proposed in [High-Resolution Image Synthesis with Latent Diffusion Models](https://huggingface.co/papers/2112.10752) by Robin Rombach, Andreas Blattmann, Dominik Lorenz, Patrick Esser, Björn Ommer.
|
| 20 |
+
|
| 21 |
+
Stable Diffusion is trained on 512x512 images from a subset of the LAION-5B dataset. This model uses a frozen CLIP ViT-L/14 text encoder to condition the model on text prompts. With its 860M UNet and 123M text encoder, the model is relatively lightweight and can run on consumer GPUs.
|
| 22 |
+
|
| 23 |
+
For more details about how Stable Diffusion works and how it differs from the base latent diffusion model, take a look at the Stability AI [announcement](https://stability.ai/blog/stable-diffusion-announcement) and our own [blog post](https://huggingface.co/blog/stable_diffusion#how-does-stable-diffusion-work) for more technical details.
|
| 24 |
+
|
| 25 |
+
You can find the original codebase for Stable Diffusion v1.0 at [CompVis/stable-diffusion](https://github.com/CompVis/stable-diffusion) and Stable Diffusion v2.0 at [Stability-AI/stablediffusion](https://github.com/Stability-AI/stablediffusion) as well as their original scripts for various tasks. Additional official checkpoints for the different Stable Diffusion versions and tasks can be found on the [CompVis](https://huggingface.co/CompVis), [Runway](https://huggingface.co/runwayml), and [Stability AI](https://huggingface.co/stabilityai) Hub organizations. Explore these organizations to find the best checkpoint for your use-case!
|
| 26 |
+
|
| 27 |
+
The table below summarizes the available Stable Diffusion pipelines, their supported tasks, and an interactive demo:
|
| 28 |
+
|
| 29 |
+
<div class="flex justify-center">
|
| 30 |
+
<div class="rounded-xl border border-gray-200">
|
| 31 |
+
<table class="min-w-full divide-y-2 divide-gray-200 bg-white text-sm">
|
| 32 |
+
<thead>
|
| 33 |
+
<tr>
|
| 34 |
+
<th class="px-4 py-2 font-medium text-gray-900 text-left">
|
| 35 |
+
Pipeline
|
| 36 |
+
</th>
|
| 37 |
+
<th class="px-4 py-2 font-medium text-gray-900 text-left">
|
| 38 |
+
Supported tasks
|
| 39 |
+
</th>
|
| 40 |
+
<th class="px-4 py-2 font-medium text-gray-900 text-left">
|
| 41 |
+
🤗 Space
|
| 42 |
+
</th>
|
| 43 |
+
</tr>
|
| 44 |
+
</thead>
|
| 45 |
+
<tbody class="divide-y divide-gray-200">
|
| 46 |
+
<tr>
|
| 47 |
+
<td class="px-4 py-2 text-gray-700">
|
| 48 |
+
<a href="./text2img">StableDiffusion</a>
|
| 49 |
+
</td>
|
| 50 |
+
<td class="px-4 py-2 text-gray-700">text-to-image</td>
|
| 51 |
+
<td class="px-4 py-2"><a href="https://huggingface.co/spaces/stabilityai/stable-diffusion"><img src="https://img.shields.io/badge/%F0%9F%A4%97%20Hugging%20Face-Spaces-blue"/></a>
|
| 52 |
+
</td>
|
| 53 |
+
</tr>
|
| 54 |
+
<tr>
|
| 55 |
+
<td class="px-4 py-2 text-gray-700">
|
| 56 |
+
<a href="./img2img">StableDiffusionImg2Img</a>
|
| 57 |
+
</td>
|
| 58 |
+
<td class="px-4 py-2 text-gray-700">image-to-image</td>
|
| 59 |
+
<td class="px-4 py-2"><a href="https://huggingface.co/spaces/huggingface/diffuse-the-rest"><img src="https://img.shields.io/badge/%F0%9F%A4%97%20Hugging%20Face-Spaces-blue"/></a>
|
| 60 |
+
</td>
|
| 61 |
+
</tr>
|
| 62 |
+
<tr>
|
| 63 |
+
<td class="px-4 py-2 text-gray-700">
|
| 64 |
+
<a href="./inpaint">StableDiffusionInpaint</a>
|
| 65 |
+
</td>
|
| 66 |
+
<td class="px-4 py-2 text-gray-700">inpainting</td>
|
| 67 |
+
<td class="px-4 py-2"><a href="https://huggingface.co/spaces/runwayml/stable-diffusion-inpainting"><img src="https://img.shields.io/badge/%F0%9F%A4%97%20Hugging%20Face-Spaces-blue"/></a>
|
| 68 |
+
</td>
|
| 69 |
+
</tr>
|
| 70 |
+
<tr>
|
| 71 |
+
<td class="px-4 py-2 text-gray-700">
|
| 72 |
+
<a href="./depth2img">StableDiffusionDepth2Img</a>
|
| 73 |
+
</td>
|
| 74 |
+
<td class="px-4 py-2 text-gray-700">depth-to-image</td>
|
| 75 |
+
<td class="px-4 py-2"><a href="https://huggingface.co/spaces/radames/stable-diffusion-depth2img"><img src="https://img.shields.io/badge/%F0%9F%A4%97%20Hugging%20Face-Spaces-blue"/></a>
|
| 76 |
+
</td>
|
| 77 |
+
</tr>
|
| 78 |
+
<tr>
|
| 79 |
+
<td class="px-4 py-2 text-gray-700">
|
| 80 |
+
<a href="./image_variation">StableDiffusionImageVariation</a>
|
| 81 |
+
</td>
|
| 82 |
+
<td class="px-4 py-2 text-gray-700">image variation</td>
|
| 83 |
+
<td class="px-4 py-2"><a href="https://huggingface.co/spaces/lambdalabs/stable-diffusion-image-variations"><img src="https://img.shields.io/badge/%F0%9F%A4%97%20Hugging%20Face-Spaces-blue"/></a>
|
| 84 |
+
</td>
|
| 85 |
+
</tr>
|
| 86 |
+
<tr>
|
| 87 |
+
<td class="px-4 py-2 text-gray-700">
|
| 88 |
+
<a href="./stable_diffusion_safe">StableDiffusionPipelineSafe</a>
|
| 89 |
+
</td>
|
| 90 |
+
<td class="px-4 py-2 text-gray-700">filtered text-to-image</td>
|
| 91 |
+
<td class="px-4 py-2"><a href="https://huggingface.co/spaces/AIML-TUDA/unsafe-vs-safe-stable-diffusion"><img src="https://img.shields.io/badge/%F0%9F%A4%97%20Hugging%20Face-Spaces-blue"/></a>
|
| 92 |
+
</td>
|
| 93 |
+
</tr>
|
| 94 |
+
<tr>
|
| 95 |
+
<td class="px-4 py-2 text-gray-700">
|
| 96 |
+
<a href="./stable_diffusion_2">StableDiffusion2</a>
|
| 97 |
+
</td>
|
| 98 |
+
<td class="px-4 py-2 text-gray-700">text-to-image, inpainting, depth-to-image, super-resolution</td>
|
| 99 |
+
<td class="px-4 py-2"><a href="https://huggingface.co/spaces/stabilityai/stable-diffusion"><img src="https://img.shields.io/badge/%F0%9F%A4%97%20Hugging%20Face-Spaces-blue"/></a>
|
| 100 |
+
</td>
|
| 101 |
+
</tr>
|
| 102 |
+
<tr>
|
| 103 |
+
<td class="px-4 py-2 text-gray-700">
|
| 104 |
+
<a href="./stable_diffusion_xl">StableDiffusionXL</a>
|
| 105 |
+
</td>
|
| 106 |
+
<td class="px-4 py-2 text-gray-700">text-to-image, image-to-image</td>
|
| 107 |
+
<td class="px-4 py-2"><a href="https://huggingface.co/spaces/RamAnanth1/stable-diffusion-xl"><img src="https://img.shields.io/badge/%F0%9F%A4%97%20Hugging%20Face-Spaces-blue"/></a>
|
| 108 |
+
</td>
|
| 109 |
+
</tr>
|
| 110 |
+
<tr>
|
| 111 |
+
<td class="px-4 py-2 text-gray-700">
|
| 112 |
+
<a href="./latent_upscale">StableDiffusionLatentUpscale</a>
|
| 113 |
+
</td>
|
| 114 |
+
<td class="px-4 py-2 text-gray-700">super-resolution</td>
|
| 115 |
+
<td class="px-4 py-2"><a href="https://huggingface.co/spaces/huggingface-projects/stable-diffusion-latent-upscaler"><img src="https://img.shields.io/badge/%F0%9F%A4%97%20Hugging%20Face-Spaces-blue"/></a>
|
| 116 |
+
</td>
|
| 117 |
+
</tr>
|
| 118 |
+
<tr>
|
| 119 |
+
<td class="px-4 py-2 text-gray-700">
|
| 120 |
+
<a href="./upscale">StableDiffusionUpscale</a>
|
| 121 |
+
</td>
|
| 122 |
+
<td class="px-4 py-2 text-gray-700">super-resolution</td>
|
| 123 |
+
</tr>
|
| 124 |
+
<tr>
|
| 125 |
+
<td class="px-4 py-2 text-gray-700">
|
| 126 |
+
<a href="./ldm3d_diffusion">StableDiffusionLDM3D</a>
|
| 127 |
+
</td>
|
| 128 |
+
<td class="px-4 py-2 text-gray-700">text-to-rgb, text-to-depth, text-to-pano</td>
|
| 129 |
+
<td class="px-4 py-2"><a href="https://huggingface.co/spaces/r23/ldm3d-space"><img src="https://img.shields.io/badge/%F0%9F%A4%97%20Hugging%20Face-Spaces-blue"/></a>
|
| 130 |
+
</td>
|
| 131 |
+
</tr>
|
| 132 |
+
<tr>
|
| 133 |
+
<td class="px-4 py-2 text-gray-700">
|
| 134 |
+
<a href="./ldm3d_diffusion">StableDiffusionUpscaleLDM3D</a>
|
| 135 |
+
</td>
|
| 136 |
+
<td class="px-4 py-2 text-gray-700">ldm3d super-resolution</td>
|
| 137 |
+
</tr>
|
| 138 |
+
</tbody>
|
| 139 |
+
</table>
|
| 140 |
+
</div>
|
| 141 |
+
</div>
|
| 142 |
+
|
| 143 |
+
## Tips
|
| 144 |
+
|
| 145 |
+
To help you get the most out of the Stable Diffusion pipelines, here are a few tips for improving performance and usability. These tips are applicable to all Stable Diffusion pipelines.
|
| 146 |
+
|
| 147 |
+
### Explore tradeoff between speed and quality
|
| 148 |
+
|
| 149 |
+
[`StableDiffusionPipeline`] uses the [`PNDMScheduler`] by default, but 🤗 Diffusers provides many other schedulers (some of which are faster or output better quality) that are compatible. For example, if you want to use the [`EulerDiscreteScheduler`] instead of the default:
|
| 150 |
+
|
| 151 |
+
```py
|
| 152 |
+
from diffusers import StableDiffusionPipeline, EulerDiscreteScheduler
|
| 153 |
+
|
| 154 |
+
pipeline = StableDiffusionPipeline.from_pretrained("CompVis/stable-diffusion-v1-4")
|
| 155 |
+
pipeline.scheduler = EulerDiscreteScheduler.from_config(pipeline.scheduler.config)
|
| 156 |
+
|
| 157 |
+
# or
|
| 158 |
+
euler_scheduler = EulerDiscreteScheduler.from_pretrained("CompVis/stable-diffusion-v1-4", subfolder="scheduler")
|
| 159 |
+
pipeline = StableDiffusionPipeline.from_pretrained("CompVis/stable-diffusion-v1-4", scheduler=euler_scheduler)
|
| 160 |
+
```
|
| 161 |
+
|
| 162 |
+
### Reuse pipeline components to save memory
|
| 163 |
+
|
| 164 |
+
To save memory and use the same components across multiple pipelines, use the `.components` method to avoid loading weights into RAM more than once.
|
| 165 |
+
|
| 166 |
+
```py
|
| 167 |
+
from diffusers import (
|
| 168 |
+
StableDiffusionPipeline,
|
| 169 |
+
StableDiffusionImg2ImgPipeline,
|
| 170 |
+
StableDiffusionInpaintPipeline,
|
| 171 |
+
)
|
| 172 |
+
|
| 173 |
+
text2img = StableDiffusionPipeline.from_pretrained("CompVis/stable-diffusion-v1-4")
|
| 174 |
+
img2img = StableDiffusionImg2ImgPipeline(**text2img.components)
|
| 175 |
+
inpaint = StableDiffusionInpaintPipeline(**text2img.components)
|
| 176 |
+
|
| 177 |
+
# now you can use text2img(...), img2img(...), inpaint(...) just like the call methods of each respective pipeline
|
| 178 |
+
```
|
| 179 |
+
|
| 180 |
+
### Create web demos using `gradio`
|
| 181 |
+
|
| 182 |
+
The Stable Diffusion pipelines are automatically supported in [Gradio](https://github.com/gradio-app/gradio/), a library that makes creating beautiful and user-friendly machine learning apps on the web a breeze. First, make sure you have Gradio installed:
|
| 183 |
+
|
| 184 |
+
```sh
|
| 185 |
+
pip install -U gradio
|
| 186 |
+
```
|
| 187 |
+
|
| 188 |
+
Then, create a web demo around any Stable Diffusion-based pipeline. For example, you can create an image generation pipeline in a single line of code with Gradio's [`Interface.from_pipeline`](https://www.gradio.app/docs/interface#interface-from-pipeline) function:
|
| 189 |
+
|
| 190 |
+
```py
|
| 191 |
+
from diffusers import StableDiffusionPipeline
|
| 192 |
+
import gradio as gr
|
| 193 |
+
|
| 194 |
+
pipe = StableDiffusionPipeline.from_pretrained("CompVis/stable-diffusion-v1-4")
|
| 195 |
+
|
| 196 |
+
gr.Interface.from_pipeline(pipe).launch()
|
| 197 |
+
```
|
| 198 |
+
|
| 199 |
+
which opens an intuitive drag-and-drop interface in your browser:
|
| 200 |
+
|
| 201 |
+
|
| 202 |
+
|
| 203 |
+
Similarly, you could create a demo for an image-to-image pipeline with:
|
| 204 |
+
|
| 205 |
+
```py
|
| 206 |
+
from diffusers import StableDiffusionImg2ImgPipeline
|
| 207 |
+
import gradio as gr
|
| 208 |
+
|
| 209 |
+
|
| 210 |
+
pipe = StableDiffusionImg2ImgPipeline.from_pretrained("stable-diffusion-v1-5/stable-diffusion-v1-5")
|
| 211 |
+
|
| 212 |
+
gr.Interface.from_pipeline(pipe).launch()
|
| 213 |
+
```
|
| 214 |
+
|
| 215 |
+
By default, the web demo runs on a local server. If you'd like to share it with others, you can generate a temporary public
|
| 216 |
+
link by setting `share=True` in `launch()`. Or, you can host your demo on [Hugging Face Spaces](https://huggingface.co/spaces)https://huggingface.co/spaces for a permanent link.
|
tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/stable_diffusion/sdxl_turbo.md
ADDED
|
@@ -0,0 +1,35 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# SDXL Turbo
|
| 14 |
+
|
| 15 |
+
Stable Diffusion XL (SDXL) Turbo was proposed in [Adversarial Diffusion Distillation](https://stability.ai/research/adversarial-diffusion-distillation) by Axel Sauer, Dominik Lorenz, Andreas Blattmann, and Robin Rombach.
|
| 16 |
+
|
| 17 |
+
The abstract from the paper is:
|
| 18 |
+
|
| 19 |
+
*We introduce Adversarial Diffusion Distillation (ADD), a novel training approach that efficiently samples large-scale foundational image diffusion models in just 1–4 steps while maintaining high image quality. We use score distillation to leverage large-scale off-the-shelf image diffusion models as a teacher signal in combination with an adversarial loss to ensure high image fidelity even in the low-step regime of one or two sampling steps. Our analyses show that our model clearly outperforms existing few-step methods (GANs,Latent Consistency Models) in a single step and reaches the performance of state-of-the-art diffusion models (SDXL) in only four steps. ADD is the first method to unlock single-step, real-time image synthesis with foundation models.*
|
| 20 |
+
|
| 21 |
+
## Tips
|
| 22 |
+
|
| 23 |
+
- SDXL Turbo uses the exact same architecture as [SDXL](./stable_diffusion_xl), which means it also has the same API. Please refer to the [SDXL](./stable_diffusion_xl) API reference for more details.
|
| 24 |
+
- SDXL Turbo should disable guidance scale by setting `guidance_scale=0.0`.
|
| 25 |
+
- SDXL Turbo should use `timestep_spacing='trailing'` for the scheduler and use between 1 and 4 steps.
|
| 26 |
+
- SDXL Turbo has been trained to generate images of size 512x512.
|
| 27 |
+
- SDXL Turbo is open-access, but not open-source meaning that one might have to buy a model license in order to use it for commercial applications. Make sure to read the [official model card](https://huggingface.co/stabilityai/sdxl-turbo) to learn more.
|
| 28 |
+
|
| 29 |
+
<Tip>
|
| 30 |
+
|
| 31 |
+
To learn how to use SDXL Turbo for various tasks, how to optimize performance, and other usage examples, take a look at the [SDXL Turbo](../../../using-diffusers/sdxl_turbo) guide.
|
| 32 |
+
|
| 33 |
+
Check out the [Stability AI](https://huggingface.co/stabilityai) Hub organization for the official base and refiner model checkpoints!
|
| 34 |
+
|
| 35 |
+
</Tip>
|
tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/stable_diffusion/stable_diffusion_2.md
ADDED
|
@@ -0,0 +1,125 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Stable Diffusion 2
|
| 14 |
+
|
| 15 |
+
Stable Diffusion 2 is a text-to-image _latent diffusion_ model built upon the work of the original [Stable Diffusion](https://stability.ai/blog/stable-diffusion-public-release), and it was led by Robin Rombach and Katherine Crowson from [Stability AI](https://stability.ai/) and [LAION](https://laion.ai/).
|
| 16 |
+
|
| 17 |
+
*The Stable Diffusion 2.0 release includes robust text-to-image models trained using a brand new text encoder (OpenCLIP), developed by LAION with support from Stability AI, which greatly improves the quality of the generated images compared to earlier V1 releases. The text-to-image models in this release can generate images with default resolutions of both 512x512 pixels and 768x768 pixels.
|
| 18 |
+
These models are trained on an aesthetic subset of the [LAION-5B dataset](https://laion.ai/blog/laion-5b/) created by the DeepFloyd team at Stability AI, which is then further filtered to remove adult content using [LAION’s NSFW filter](https://openreview.net/forum?id=M3Y74vmsMcY).*
|
| 19 |
+
|
| 20 |
+
For more details about how Stable Diffusion 2 works and how it differs from the original Stable Diffusion, please refer to the official [announcement post](https://stability.ai/blog/stable-diffusion-v2-release).
|
| 21 |
+
|
| 22 |
+
The architecture of Stable Diffusion 2 is more or less identical to the original [Stable Diffusion model](./text2img) so check out it's API documentation for how to use Stable Diffusion 2. We recommend using the [`DPMSolverMultistepScheduler`] as it gives a reasonable speed/quality trade-off and can be run with as little as 20 steps.
|
| 23 |
+
|
| 24 |
+
Stable Diffusion 2 is available for tasks like text-to-image, inpainting, super-resolution, and depth-to-image:
|
| 25 |
+
|
| 26 |
+
| Task | Repository |
|
| 27 |
+
|-------------------------|---------------------------------------------------------------------------------------------------------------|
|
| 28 |
+
| text-to-image (512x512) | [stabilityai/stable-diffusion-2-base](https://huggingface.co/stabilityai/stable-diffusion-2-base) |
|
| 29 |
+
| text-to-image (768x768) | [stabilityai/stable-diffusion-2](https://huggingface.co/stabilityai/stable-diffusion-2) |
|
| 30 |
+
| inpainting | [stabilityai/stable-diffusion-2-inpainting](https://huggingface.co/stabilityai/stable-diffusion-2-inpainting) |
|
| 31 |
+
| super-resolution | [stable-diffusion-x4-upscaler](https://huggingface.co/stabilityai/stable-diffusion-x4-upscaler) |
|
| 32 |
+
| depth-to-image | [stabilityai/stable-diffusion-2-depth](https://huggingface.co/stabilityai/stable-diffusion-2-depth) |
|
| 33 |
+
|
| 34 |
+
Here are some examples for how to use Stable Diffusion 2 for each task:
|
| 35 |
+
|
| 36 |
+
<Tip>
|
| 37 |
+
|
| 38 |
+
Make sure to check out the Stable Diffusion [Tips](overview#tips) section to learn how to explore the tradeoff between scheduler speed and quality, and how to reuse pipeline components efficiently!
|
| 39 |
+
|
| 40 |
+
If you're interested in using one of the official checkpoints for a task, explore the [CompVis](https://huggingface.co/CompVis), [Runway](https://huggingface.co/runwayml), and [Stability AI](https://huggingface.co/stabilityai) Hub organizations!
|
| 41 |
+
|
| 42 |
+
</Tip>
|
| 43 |
+
|
| 44 |
+
## Text-to-image
|
| 45 |
+
|
| 46 |
+
```py
|
| 47 |
+
from diffusers import DiffusionPipeline, DPMSolverMultistepScheduler
|
| 48 |
+
import torch
|
| 49 |
+
|
| 50 |
+
repo_id = "stabilityai/stable-diffusion-2-base"
|
| 51 |
+
pipe = DiffusionPipeline.from_pretrained(repo_id, torch_dtype=torch.float16, variant="fp16")
|
| 52 |
+
|
| 53 |
+
pipe.scheduler = DPMSolverMultistepScheduler.from_config(pipe.scheduler.config)
|
| 54 |
+
pipe = pipe.to("cuda")
|
| 55 |
+
|
| 56 |
+
prompt = "High quality photo of an astronaut riding a horse in space"
|
| 57 |
+
image = pipe(prompt, num_inference_steps=25).images[0]
|
| 58 |
+
image
|
| 59 |
+
```
|
| 60 |
+
|
| 61 |
+
## Inpainting
|
| 62 |
+
|
| 63 |
+
```py
|
| 64 |
+
import torch
|
| 65 |
+
from diffusers import DiffusionPipeline, DPMSolverMultistepScheduler
|
| 66 |
+
from diffusers.utils import load_image, make_image_grid
|
| 67 |
+
|
| 68 |
+
img_url = "https://raw.githubusercontent.com/CompVis/latent-diffusion/main/data/inpainting_examples/overture-creations-5sI6fQgYIuo.png"
|
| 69 |
+
mask_url = "https://raw.githubusercontent.com/CompVis/latent-diffusion/main/data/inpainting_examples/overture-creations-5sI6fQgYIuo_mask.png"
|
| 70 |
+
|
| 71 |
+
init_image = load_image(img_url).resize((512, 512))
|
| 72 |
+
mask_image = load_image(mask_url).resize((512, 512))
|
| 73 |
+
|
| 74 |
+
repo_id = "stabilityai/stable-diffusion-2-inpainting"
|
| 75 |
+
pipe = DiffusionPipeline.from_pretrained(repo_id, torch_dtype=torch.float16, variant="fp16")
|
| 76 |
+
|
| 77 |
+
pipe.scheduler = DPMSolverMultistepScheduler.from_config(pipe.scheduler.config)
|
| 78 |
+
pipe = pipe.to("cuda")
|
| 79 |
+
|
| 80 |
+
prompt = "Face of a yellow cat, high resolution, sitting on a park bench"
|
| 81 |
+
image = pipe(prompt=prompt, image=init_image, mask_image=mask_image, num_inference_steps=25).images[0]
|
| 82 |
+
make_image_grid([init_image, mask_image, image], rows=1, cols=3)
|
| 83 |
+
```
|
| 84 |
+
|
| 85 |
+
## Super-resolution
|
| 86 |
+
|
| 87 |
+
```py
|
| 88 |
+
from diffusers import StableDiffusionUpscalePipeline
|
| 89 |
+
from diffusers.utils import load_image, make_image_grid
|
| 90 |
+
import torch
|
| 91 |
+
|
| 92 |
+
# load model and scheduler
|
| 93 |
+
model_id = "stabilityai/stable-diffusion-x4-upscaler"
|
| 94 |
+
pipeline = StableDiffusionUpscalePipeline.from_pretrained(model_id, torch_dtype=torch.float16)
|
| 95 |
+
pipeline = pipeline.to("cuda")
|
| 96 |
+
|
| 97 |
+
# let's download an image
|
| 98 |
+
url = "https://huggingface.co/datasets/hf-internal-testing/diffusers-images/resolve/main/sd2-upscale/low_res_cat.png"
|
| 99 |
+
low_res_img = load_image(url)
|
| 100 |
+
low_res_img = low_res_img.resize((128, 128))
|
| 101 |
+
prompt = "a white cat"
|
| 102 |
+
upscaled_image = pipeline(prompt=prompt, image=low_res_img).images[0]
|
| 103 |
+
make_image_grid([low_res_img.resize((512, 512)), upscaled_image.resize((512, 512))], rows=1, cols=2)
|
| 104 |
+
```
|
| 105 |
+
|
| 106 |
+
## Depth-to-image
|
| 107 |
+
|
| 108 |
+
```py
|
| 109 |
+
import torch
|
| 110 |
+
from diffusers import StableDiffusionDepth2ImgPipeline
|
| 111 |
+
from diffusers.utils import load_image, make_image_grid
|
| 112 |
+
|
| 113 |
+
pipe = StableDiffusionDepth2ImgPipeline.from_pretrained(
|
| 114 |
+
"stabilityai/stable-diffusion-2-depth",
|
| 115 |
+
torch_dtype=torch.float16,
|
| 116 |
+
).to("cuda")
|
| 117 |
+
|
| 118 |
+
|
| 119 |
+
url = "http://images.cocodataset.org/val2017/000000039769.jpg"
|
| 120 |
+
init_image = load_image(url)
|
| 121 |
+
prompt = "two tigers"
|
| 122 |
+
negative_prompt = "bad, deformed, ugly, bad anotomy"
|
| 123 |
+
image = pipe(prompt=prompt, image=init_image, negative_prompt=negative_prompt, strength=0.7).images[0]
|
| 124 |
+
make_image_grid([init_image, image], rows=1, cols=2)
|
| 125 |
+
```
|
tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/stable_diffusion/stable_diffusion_3.md
ADDED
|
@@ -0,0 +1,452 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Stable Diffusion 3
|
| 14 |
+
|
| 15 |
+
<div class="flex flex-wrap space-x-1">
|
| 16 |
+
<img alt="LoRA" src="https://img.shields.io/badge/LoRA-d8b4fe?style=flat"/>
|
| 17 |
+
<img alt="MPS" src="https://img.shields.io/badge/MPS-000000?style=flat&logo=apple&logoColor=white%22">
|
| 18 |
+
</div>
|
| 19 |
+
|
| 20 |
+
Stable Diffusion 3 (SD3) was proposed in [Scaling Rectified Flow Transformers for High-Resolution Image Synthesis](https://huggingface.co/papers/2403.03206) by Patrick Esser, Sumith Kulal, Andreas Blattmann, Rahim Entezari, Jonas Muller, Harry Saini, Yam Levi, Dominik Lorenz, Axel Sauer, Frederic Boesel, Dustin Podell, Tim Dockhorn, Zion English, Kyle Lacey, Alex Goodwin, Yannik Marek, and Robin Rombach.
|
| 21 |
+
|
| 22 |
+
The abstract from the paper is:
|
| 23 |
+
|
| 24 |
+
*Diffusion models create data from noise by inverting the forward paths of data towards noise and have emerged as a powerful generative modeling technique for high-dimensional, perceptual data such as images and videos. Rectified flow is a recent generative model formulation that connects data and noise in a straight line. Despite its better theoretical properties and conceptual simplicity, it is not yet decisively established as standard practice. In this work, we improve existing noise sampling techniques for training rectified flow models by biasing them towards perceptually relevant scales. Through a large-scale study, we demonstrate the superior performance of this approach compared to established diffusion formulations for high-resolution text-to-image synthesis. Additionally, we present a novel transformer-based architecture for text-to-image generation that uses separate weights for the two modalities and enables a bidirectional flow of information between image and text tokens, improving text comprehension typography, and human preference ratings. We demonstrate that this architecture follows predictable scaling trends and correlates lower validation loss to improved text-to-image synthesis as measured by various metrics and human evaluations.*
|
| 25 |
+
|
| 26 |
+
|
| 27 |
+
## Usage Example
|
| 28 |
+
|
| 29 |
+
_As the model is gated, before using it with diffusers you first need to go to the [Stable Diffusion 3 Medium Hugging Face page](https://huggingface.co/stabilityai/stable-diffusion-3-medium-diffusers), fill in the form and accept the gate. Once you are in, you need to login so that your system knows you’ve accepted the gate._
|
| 30 |
+
|
| 31 |
+
Use the command below to log in:
|
| 32 |
+
|
| 33 |
+
```bash
|
| 34 |
+
huggingface-cli login
|
| 35 |
+
```
|
| 36 |
+
|
| 37 |
+
<Tip>
|
| 38 |
+
|
| 39 |
+
The SD3 pipeline uses three text encoders to generate an image. Model offloading is necessary in order for it to run on most commodity hardware. Please use the `torch.float16` data type for additional memory savings.
|
| 40 |
+
|
| 41 |
+
</Tip>
|
| 42 |
+
|
| 43 |
+
```python
|
| 44 |
+
import torch
|
| 45 |
+
from diffusers import StableDiffusion3Pipeline
|
| 46 |
+
|
| 47 |
+
pipe = StableDiffusion3Pipeline.from_pretrained("stabilityai/stable-diffusion-3-medium-diffusers", torch_dtype=torch.float16)
|
| 48 |
+
pipe.to("cuda")
|
| 49 |
+
|
| 50 |
+
image = pipe(
|
| 51 |
+
prompt="a photo of a cat holding a sign that says hello world",
|
| 52 |
+
negative_prompt="",
|
| 53 |
+
num_inference_steps=28,
|
| 54 |
+
height=1024,
|
| 55 |
+
width=1024,
|
| 56 |
+
guidance_scale=7.0,
|
| 57 |
+
).images[0]
|
| 58 |
+
|
| 59 |
+
image.save("sd3_hello_world.png")
|
| 60 |
+
```
|
| 61 |
+
|
| 62 |
+
**Note:** Stable Diffusion 3.5 can also be run using the SD3 pipeline, and all mentioned optimizations and techniques apply to it as well. In total there are three official models in the SD3 family:
|
| 63 |
+
- [`stabilityai/stable-diffusion-3-medium-diffusers`](https://huggingface.co/stabilityai/stable-diffusion-3-medium-diffusers)
|
| 64 |
+
- [`stabilityai/stable-diffusion-3.5-large`](https://huggingface.co/stabilityai/stable-diffusion-3-5-large)
|
| 65 |
+
- [`stabilityai/stable-diffusion-3.5-large-turbo`](https://huggingface.co/stabilityai/stable-diffusion-3-5-large-turbo)
|
| 66 |
+
|
| 67 |
+
## Image Prompting with IP-Adapters
|
| 68 |
+
|
| 69 |
+
An IP-Adapter lets you prompt SD3 with images, in addition to the text prompt. This is especially useful when describing complex concepts that are difficult to articulate through text alone and you have reference images. To load and use an IP-Adapter, you need:
|
| 70 |
+
|
| 71 |
+
- `image_encoder`: Pre-trained vision model used to obtain image features, usually a CLIP image encoder.
|
| 72 |
+
- `feature_extractor`: Image processor that prepares the input image for the chosen `image_encoder`.
|
| 73 |
+
- `ip_adapter_id`: Checkpoint containing parameters of image cross attention layers and image projection.
|
| 74 |
+
|
| 75 |
+
IP-Adapters are trained for a specific model architecture, so they also work in finetuned variations of the base model. You can use the [`~SD3IPAdapterMixin.set_ip_adapter_scale`] function to adjust how strongly the output aligns with the image prompt. The higher the value, the more closely the model follows the image prompt. A default value of 0.5 is typically a good balance, ensuring the model considers both the text and image prompts equally.
|
| 76 |
+
|
| 77 |
+
```python
|
| 78 |
+
import torch
|
| 79 |
+
from PIL import Image
|
| 80 |
+
|
| 81 |
+
from diffusers import StableDiffusion3Pipeline
|
| 82 |
+
from transformers import SiglipVisionModel, SiglipImageProcessor
|
| 83 |
+
|
| 84 |
+
image_encoder_id = "google/siglip-so400m-patch14-384"
|
| 85 |
+
ip_adapter_id = "InstantX/SD3.5-Large-IP-Adapter"
|
| 86 |
+
|
| 87 |
+
feature_extractor = SiglipImageProcessor.from_pretrained(
|
| 88 |
+
image_encoder_id,
|
| 89 |
+
torch_dtype=torch.float16
|
| 90 |
+
)
|
| 91 |
+
image_encoder = SiglipVisionModel.from_pretrained(
|
| 92 |
+
image_encoder_id,
|
| 93 |
+
torch_dtype=torch.float16
|
| 94 |
+
).to( "cuda")
|
| 95 |
+
|
| 96 |
+
pipe = StableDiffusion3Pipeline.from_pretrained(
|
| 97 |
+
"stabilityai/stable-diffusion-3.5-large",
|
| 98 |
+
torch_dtype=torch.float16,
|
| 99 |
+
feature_extractor=feature_extractor,
|
| 100 |
+
image_encoder=image_encoder,
|
| 101 |
+
).to("cuda")
|
| 102 |
+
|
| 103 |
+
pipe.load_ip_adapter(ip_adapter_id)
|
| 104 |
+
pipe.set_ip_adapter_scale(0.6)
|
| 105 |
+
|
| 106 |
+
ref_img = Image.open("image.jpg").convert('RGB')
|
| 107 |
+
|
| 108 |
+
image = pipe(
|
| 109 |
+
width=1024,
|
| 110 |
+
height=1024,
|
| 111 |
+
prompt="a cat",
|
| 112 |
+
negative_prompt="lowres, low quality, worst quality",
|
| 113 |
+
num_inference_steps=24,
|
| 114 |
+
guidance_scale=5.0,
|
| 115 |
+
ip_adapter_image=ref_img
|
| 116 |
+
).images[0]
|
| 117 |
+
|
| 118 |
+
image.save("result.jpg")
|
| 119 |
+
```
|
| 120 |
+
|
| 121 |
+
<div class="justify-center">
|
| 122 |
+
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/sd3_ip_adapter_example.png"/>
|
| 123 |
+
<figcaption class="mt-2 text-sm text-center text-gray-500">IP-Adapter examples with prompt "a cat"</figcaption>
|
| 124 |
+
</div>
|
| 125 |
+
|
| 126 |
+
|
| 127 |
+
<Tip>
|
| 128 |
+
|
| 129 |
+
Check out [IP-Adapter](../../../using-diffusers/ip_adapter) to learn more about how IP-Adapters work.
|
| 130 |
+
|
| 131 |
+
</Tip>
|
| 132 |
+
|
| 133 |
+
|
| 134 |
+
## Memory Optimisations for SD3
|
| 135 |
+
|
| 136 |
+
SD3 uses three text encoders, one of which is the very large T5-XXL model. This makes it challenging to run the model on GPUs with less than 24GB of VRAM, even when using `fp16` precision. The following section outlines a few memory optimizations in Diffusers that make it easier to run SD3 on low resource hardware.
|
| 137 |
+
|
| 138 |
+
### Running Inference with Model Offloading
|
| 139 |
+
|
| 140 |
+
The most basic memory optimization available in Diffusers allows you to offload the components of the model to CPU during inference in order to save memory, while seeing a slight increase in inference latency. Model offloading will only move a model component onto the GPU when it needs to be executed, while keeping the remaining components on the CPU.
|
| 141 |
+
|
| 142 |
+
```python
|
| 143 |
+
import torch
|
| 144 |
+
from diffusers import StableDiffusion3Pipeline
|
| 145 |
+
|
| 146 |
+
pipe = StableDiffusion3Pipeline.from_pretrained("stabilityai/stable-diffusion-3-medium-diffusers", torch_dtype=torch.float16)
|
| 147 |
+
pipe.enable_model_cpu_offload()
|
| 148 |
+
|
| 149 |
+
image = pipe(
|
| 150 |
+
prompt="a photo of a cat holding a sign that says hello world",
|
| 151 |
+
negative_prompt="",
|
| 152 |
+
num_inference_steps=28,
|
| 153 |
+
height=1024,
|
| 154 |
+
width=1024,
|
| 155 |
+
guidance_scale=7.0,
|
| 156 |
+
).images[0]
|
| 157 |
+
|
| 158 |
+
image.save("sd3_hello_world.png")
|
| 159 |
+
```
|
| 160 |
+
|
| 161 |
+
### Dropping the T5 Text Encoder during Inference
|
| 162 |
+
|
| 163 |
+
Removing the memory-intensive 4.7B parameter T5-XXL text encoder during inference can significantly decrease the memory requirements for SD3 with only a slight loss in performance.
|
| 164 |
+
|
| 165 |
+
```python
|
| 166 |
+
import torch
|
| 167 |
+
from diffusers import StableDiffusion3Pipeline
|
| 168 |
+
|
| 169 |
+
pipe = StableDiffusion3Pipeline.from_pretrained(
|
| 170 |
+
"stabilityai/stable-diffusion-3-medium-diffusers",
|
| 171 |
+
text_encoder_3=None,
|
| 172 |
+
tokenizer_3=None,
|
| 173 |
+
torch_dtype=torch.float16
|
| 174 |
+
)
|
| 175 |
+
pipe.to("cuda")
|
| 176 |
+
|
| 177 |
+
image = pipe(
|
| 178 |
+
prompt="a photo of a cat holding a sign that says hello world",
|
| 179 |
+
negative_prompt="",
|
| 180 |
+
num_inference_steps=28,
|
| 181 |
+
height=1024,
|
| 182 |
+
width=1024,
|
| 183 |
+
guidance_scale=7.0,
|
| 184 |
+
).images[0]
|
| 185 |
+
|
| 186 |
+
image.save("sd3_hello_world-no-T5.png")
|
| 187 |
+
```
|
| 188 |
+
|
| 189 |
+
### Using a Quantized Version of the T5 Text Encoder
|
| 190 |
+
|
| 191 |
+
We can leverage the `bitsandbytes` library to load and quantize the T5-XXL text encoder to 8-bit precision. This allows you to keep using all three text encoders while only slightly impacting performance.
|
| 192 |
+
|
| 193 |
+
First install the `bitsandbytes` library.
|
| 194 |
+
|
| 195 |
+
```shell
|
| 196 |
+
pip install bitsandbytes
|
| 197 |
+
```
|
| 198 |
+
|
| 199 |
+
Then load the T5-XXL model using the `BitsAndBytesConfig`.
|
| 200 |
+
|
| 201 |
+
```python
|
| 202 |
+
import torch
|
| 203 |
+
from diffusers import StableDiffusion3Pipeline
|
| 204 |
+
from transformers import T5EncoderModel, BitsAndBytesConfig
|
| 205 |
+
|
| 206 |
+
quantization_config = BitsAndBytesConfig(load_in_8bit=True)
|
| 207 |
+
|
| 208 |
+
model_id = "stabilityai/stable-diffusion-3-medium-diffusers"
|
| 209 |
+
text_encoder = T5EncoderModel.from_pretrained(
|
| 210 |
+
model_id,
|
| 211 |
+
subfolder="text_encoder_3",
|
| 212 |
+
quantization_config=quantization_config,
|
| 213 |
+
)
|
| 214 |
+
pipe = StableDiffusion3Pipeline.from_pretrained(
|
| 215 |
+
model_id,
|
| 216 |
+
text_encoder_3=text_encoder,
|
| 217 |
+
device_map="balanced",
|
| 218 |
+
torch_dtype=torch.float16
|
| 219 |
+
)
|
| 220 |
+
|
| 221 |
+
image = pipe(
|
| 222 |
+
prompt="a photo of a cat holding a sign that says hello world",
|
| 223 |
+
negative_prompt="",
|
| 224 |
+
num_inference_steps=28,
|
| 225 |
+
height=1024,
|
| 226 |
+
width=1024,
|
| 227 |
+
guidance_scale=7.0,
|
| 228 |
+
).images[0]
|
| 229 |
+
|
| 230 |
+
image.save("sd3_hello_world-8bit-T5.png")
|
| 231 |
+
```
|
| 232 |
+
|
| 233 |
+
You can find the end-to-end script [here](https://gist.github.com/sayakpaul/82acb5976509851f2db1a83456e504f1).
|
| 234 |
+
|
| 235 |
+
## Performance Optimizations for SD3
|
| 236 |
+
|
| 237 |
+
### Using Torch Compile to Speed Up Inference
|
| 238 |
+
|
| 239 |
+
Using compiled components in the SD3 pipeline can speed up inference by as much as 4X. The following code snippet demonstrates how to compile the Transformer and VAE components of the SD3 pipeline.
|
| 240 |
+
|
| 241 |
+
```python
|
| 242 |
+
import torch
|
| 243 |
+
from diffusers import StableDiffusion3Pipeline
|
| 244 |
+
|
| 245 |
+
torch.set_float32_matmul_precision("high")
|
| 246 |
+
|
| 247 |
+
torch._inductor.config.conv_1x1_as_mm = True
|
| 248 |
+
torch._inductor.config.coordinate_descent_tuning = True
|
| 249 |
+
torch._inductor.config.epilogue_fusion = False
|
| 250 |
+
torch._inductor.config.coordinate_descent_check_all_directions = True
|
| 251 |
+
|
| 252 |
+
pipe = StableDiffusion3Pipeline.from_pretrained(
|
| 253 |
+
"stabilityai/stable-diffusion-3-medium-diffusers",
|
| 254 |
+
torch_dtype=torch.float16
|
| 255 |
+
).to("cuda")
|
| 256 |
+
pipe.set_progress_bar_config(disable=True)
|
| 257 |
+
|
| 258 |
+
pipe.transformer.to(memory_format=torch.channels_last)
|
| 259 |
+
pipe.vae.to(memory_format=torch.channels_last)
|
| 260 |
+
|
| 261 |
+
pipe.transformer = torch.compile(pipe.transformer, mode="max-autotune", fullgraph=True)
|
| 262 |
+
pipe.vae.decode = torch.compile(pipe.vae.decode, mode="max-autotune", fullgraph=True)
|
| 263 |
+
|
| 264 |
+
# Warm Up
|
| 265 |
+
prompt = "a photo of a cat holding a sign that says hello world"
|
| 266 |
+
for _ in range(3):
|
| 267 |
+
_ = pipe(prompt=prompt, generator=torch.manual_seed(1))
|
| 268 |
+
|
| 269 |
+
# Run Inference
|
| 270 |
+
image = pipe(prompt=prompt, generator=torch.manual_seed(1)).images[0]
|
| 271 |
+
image.save("sd3_hello_world.png")
|
| 272 |
+
```
|
| 273 |
+
|
| 274 |
+
Check out the full script [here](https://gist.github.com/sayakpaul/508d89d7aad4f454900813da5d42ca97).
|
| 275 |
+
|
| 276 |
+
## Quantization
|
| 277 |
+
|
| 278 |
+
Quantization helps reduce the memory requirements of very large models by storing model weights in a lower precision data type. However, quantization may have varying impact on video quality depending on the video model.
|
| 279 |
+
|
| 280 |
+
Refer to the [Quantization](../../quantization/overview) overview to learn more about supported quantization backends and selecting a quantization backend that supports your use case. The example below demonstrates how to load a quantized [`StableDiffusion3Pipeline`] for inference with bitsandbytes.
|
| 281 |
+
|
| 282 |
+
```py
|
| 283 |
+
import torch
|
| 284 |
+
from diffusers import BitsAndBytesConfig as DiffusersBitsAndBytesConfig, SD3Transformer2DModel, StableDiffusion3Pipeline
|
| 285 |
+
from transformers import BitsAndBytesConfig as BitsAndBytesConfig, T5EncoderModel
|
| 286 |
+
|
| 287 |
+
quant_config = BitsAndBytesConfig(load_in_8bit=True)
|
| 288 |
+
text_encoder_8bit = T5EncoderModel.from_pretrained(
|
| 289 |
+
"stabilityai/stable-diffusion-3.5-large",
|
| 290 |
+
subfolder="text_encoder_3",
|
| 291 |
+
quantization_config=quant_config,
|
| 292 |
+
torch_dtype=torch.float16,
|
| 293 |
+
)
|
| 294 |
+
|
| 295 |
+
quant_config = DiffusersBitsAndBytesConfig(load_in_8bit=True)
|
| 296 |
+
transformer_8bit = SD3Transformer2DModel.from_pretrained(
|
| 297 |
+
"stabilityai/stable-diffusion-3.5-large",
|
| 298 |
+
subfolder="transformer",
|
| 299 |
+
quantization_config=quant_config,
|
| 300 |
+
torch_dtype=torch.float16,
|
| 301 |
+
)
|
| 302 |
+
|
| 303 |
+
pipeline = StableDiffusion3Pipeline.from_pretrained(
|
| 304 |
+
"stabilityai/stable-diffusion-3.5-large",
|
| 305 |
+
text_encoder=text_encoder_8bit,
|
| 306 |
+
transformer=transformer_8bit,
|
| 307 |
+
torch_dtype=torch.float16,
|
| 308 |
+
device_map="balanced",
|
| 309 |
+
)
|
| 310 |
+
|
| 311 |
+
prompt = "a tiny astronaut hatching from an egg on the moon"
|
| 312 |
+
image = pipeline(prompt, num_inference_steps=28, guidance_scale=7.0).images[0]
|
| 313 |
+
image.save("sd3.png")
|
| 314 |
+
```
|
| 315 |
+
|
| 316 |
+
## Using Long Prompts with the T5 Text Encoder
|
| 317 |
+
|
| 318 |
+
By default, the T5 Text Encoder prompt uses a maximum sequence length of `256`. This can be adjusted by setting the `max_sequence_length` to accept fewer or more tokens. Keep in mind that longer sequences require additional resources and result in longer generation times, such as during batch inference.
|
| 319 |
+
|
| 320 |
+
```python
|
| 321 |
+
prompt = "A whimsical and creative image depicting a hybrid creature that is a mix of a waffle and a hippopotamus, basking in a river of melted butter amidst a breakfast-themed landscape. It features the distinctive, bulky body shape of a hippo. However, instead of the usual grey skin, the creature’s body resembles a golden-brown, crispy waffle fresh off the griddle. The skin is textured with the familiar grid pattern of a waffle, each square filled with a glistening sheen of syrup. The environment combines the natural habitat of a hippo with elements of a breakfast table setting, a river of warm, melted butter, with oversized utensils or plates peeking out from the lush, pancake-like foliage in the background, a towering pepper mill standing in for a tree. As the sun rises in this fantastical world, it casts a warm, buttery glow over the scene. The creature, content in its butter river, lets out a yawn. Nearby, a flock of birds take flight"
|
| 322 |
+
|
| 323 |
+
image = pipe(
|
| 324 |
+
prompt=prompt,
|
| 325 |
+
negative_prompt="",
|
| 326 |
+
num_inference_steps=28,
|
| 327 |
+
guidance_scale=4.5,
|
| 328 |
+
max_sequence_length=512,
|
| 329 |
+
).images[0]
|
| 330 |
+
```
|
| 331 |
+
|
| 332 |
+
### Sending a different prompt to the T5 Text Encoder
|
| 333 |
+
|
| 334 |
+
You can send a different prompt to the CLIP Text Encoders and the T5 Text Encoder to prevent the prompt from being truncated by the CLIP Text Encoders and to improve generation.
|
| 335 |
+
|
| 336 |
+
<Tip>
|
| 337 |
+
|
| 338 |
+
The prompt with the CLIP Text Encoders is still truncated to the 77 token limit.
|
| 339 |
+
|
| 340 |
+
</Tip>
|
| 341 |
+
|
| 342 |
+
```python
|
| 343 |
+
prompt = "A whimsical and creative image depicting a hybrid creature that is a mix of a waffle and a hippopotamus, basking in a river of melted butter amidst a breakfast-themed landscape. A river of warm, melted butter, pancake-like foliage in the background, a towering pepper mill standing in for a tree."
|
| 344 |
+
|
| 345 |
+
prompt_3 = "A whimsical and creative image depicting a hybrid creature that is a mix of a waffle and a hippopotamus, basking in a river of melted butter amidst a breakfast-themed landscape. It features the distinctive, bulky body shape of a hippo. However, instead of the usual grey skin, the creature’s body resembles a golden-brown, crispy waffle fresh off the griddle. The skin is textured with the familiar grid pattern of a waffle, each square filled with a glistening sheen of syrup. The environment combines the natural habitat of a hippo with elements of a breakfast table setting, a river of warm, melted butter, with oversized utensils or plates peeking out from the lush, pancake-like foliage in the background, a towering pepper mill standing in for a tree. As the sun rises in this fantastical world, it casts a warm, buttery glow over the scene. The creature, content in its butter river, lets out a yawn. Nearby, a flock of birds take flight"
|
| 346 |
+
|
| 347 |
+
image = pipe(
|
| 348 |
+
prompt=prompt,
|
| 349 |
+
prompt_3=prompt_3,
|
| 350 |
+
negative_prompt="",
|
| 351 |
+
num_inference_steps=28,
|
| 352 |
+
guidance_scale=4.5,
|
| 353 |
+
max_sequence_length=512,
|
| 354 |
+
).images[0]
|
| 355 |
+
```
|
| 356 |
+
|
| 357 |
+
## Tiny AutoEncoder for Stable Diffusion 3
|
| 358 |
+
|
| 359 |
+
Tiny AutoEncoder for Stable Diffusion (TAESD3) is a tiny distilled version of Stable Diffusion 3's VAE by [Ollin Boer Bohan](https://github.com/madebyollin/taesd) that can decode [`StableDiffusion3Pipeline`] latents almost instantly.
|
| 360 |
+
|
| 361 |
+
To use with Stable Diffusion 3:
|
| 362 |
+
|
| 363 |
+
```python
|
| 364 |
+
import torch
|
| 365 |
+
from diffusers import StableDiffusion3Pipeline, AutoencoderTiny
|
| 366 |
+
|
| 367 |
+
pipe = StableDiffusion3Pipeline.from_pretrained(
|
| 368 |
+
"stabilityai/stable-diffusion-3-medium-diffusers", torch_dtype=torch.float16
|
| 369 |
+
)
|
| 370 |
+
pipe.vae = AutoencoderTiny.from_pretrained("madebyollin/taesd3", torch_dtype=torch.float16)
|
| 371 |
+
pipe = pipe.to("cuda")
|
| 372 |
+
|
| 373 |
+
prompt = "slice of delicious New York-style berry cheesecake"
|
| 374 |
+
image = pipe(prompt, num_inference_steps=25).images[0]
|
| 375 |
+
image.save("cheesecake.png")
|
| 376 |
+
```
|
| 377 |
+
|
| 378 |
+
## Loading the original checkpoints via `from_single_file`
|
| 379 |
+
|
| 380 |
+
The `SD3Transformer2DModel` and `StableDiffusion3Pipeline` classes support loading the original checkpoints via the `from_single_file` method. This method allows you to load the original checkpoint files that were used to train the models.
|
| 381 |
+
|
| 382 |
+
## Loading the original checkpoints for the `SD3Transformer2DModel`
|
| 383 |
+
|
| 384 |
+
```python
|
| 385 |
+
from diffusers import SD3Transformer2DModel
|
| 386 |
+
|
| 387 |
+
model = SD3Transformer2DModel.from_single_file("https://huggingface.co/stabilityai/stable-diffusion-3-medium/blob/main/sd3_medium.safetensors")
|
| 388 |
+
```
|
| 389 |
+
|
| 390 |
+
## Loading the single checkpoint for the `StableDiffusion3Pipeline`
|
| 391 |
+
|
| 392 |
+
### Loading the single file checkpoint without T5
|
| 393 |
+
|
| 394 |
+
```python
|
| 395 |
+
import torch
|
| 396 |
+
from diffusers import StableDiffusion3Pipeline
|
| 397 |
+
|
| 398 |
+
pipe = StableDiffusion3Pipeline.from_single_file(
|
| 399 |
+
"https://huggingface.co/stabilityai/stable-diffusion-3-medium/blob/main/sd3_medium_incl_clips.safetensors",
|
| 400 |
+
torch_dtype=torch.float16,
|
| 401 |
+
text_encoder_3=None
|
| 402 |
+
)
|
| 403 |
+
pipe.enable_model_cpu_offload()
|
| 404 |
+
|
| 405 |
+
image = pipe("a picture of a cat holding a sign that says hello world").images[0]
|
| 406 |
+
image.save('sd3-single-file.png')
|
| 407 |
+
```
|
| 408 |
+
|
| 409 |
+
### Loading the single file checkpoint with T5
|
| 410 |
+
|
| 411 |
+
> [!TIP]
|
| 412 |
+
> The following example loads a checkpoint stored in a 8-bit floating point format which requires PyTorch 2.3 or later.
|
| 413 |
+
|
| 414 |
+
```python
|
| 415 |
+
import torch
|
| 416 |
+
from diffusers import StableDiffusion3Pipeline
|
| 417 |
+
|
| 418 |
+
pipe = StableDiffusion3Pipeline.from_single_file(
|
| 419 |
+
"https://huggingface.co/stabilityai/stable-diffusion-3-medium/blob/main/sd3_medium_incl_clips_t5xxlfp8.safetensors",
|
| 420 |
+
torch_dtype=torch.float16,
|
| 421 |
+
)
|
| 422 |
+
pipe.enable_model_cpu_offload()
|
| 423 |
+
|
| 424 |
+
image = pipe("a picture of a cat holding a sign that says hello world").images[0]
|
| 425 |
+
image.save('sd3-single-file-t5-fp8.png')
|
| 426 |
+
```
|
| 427 |
+
|
| 428 |
+
### Loading the single file checkpoint for the Stable Diffusion 3.5 Transformer Model
|
| 429 |
+
|
| 430 |
+
```python
|
| 431 |
+
import torch
|
| 432 |
+
from diffusers import SD3Transformer2DModel, StableDiffusion3Pipeline
|
| 433 |
+
|
| 434 |
+
transformer = SD3Transformer2DModel.from_single_file(
|
| 435 |
+
"https://huggingface.co/stabilityai/stable-diffusion-3.5-large-turbo/blob/main/sd3.5_large.safetensors",
|
| 436 |
+
torch_dtype=torch.bfloat16,
|
| 437 |
+
)
|
| 438 |
+
pipe = StableDiffusion3Pipeline.from_pretrained(
|
| 439 |
+
"stabilityai/stable-diffusion-3.5-large",
|
| 440 |
+
transformer=transformer,
|
| 441 |
+
torch_dtype=torch.bfloat16,
|
| 442 |
+
)
|
| 443 |
+
pipe.enable_model_cpu_offload()
|
| 444 |
+
image = pipe("a cat holding a sign that says hello world").images[0]
|
| 445 |
+
image.save("sd35.png")
|
| 446 |
+
```
|
| 447 |
+
|
| 448 |
+
## StableDiffusion3Pipeline
|
| 449 |
+
|
| 450 |
+
[[autodoc]] StableDiffusion3Pipeline
|
| 451 |
+
- all
|
| 452 |
+
- __call__
|
tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/stable_diffusion/stable_diffusion_safe.md
ADDED
|
@@ -0,0 +1,61 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Safe Stable Diffusion
|
| 14 |
+
|
| 15 |
+
Safe Stable Diffusion was proposed in [Safe Latent Diffusion: Mitigating Inappropriate Degeneration in Diffusion Models](https://huggingface.co/papers/2211.05105) and mitigates inappropriate degeneration from Stable Diffusion models because they're trained on unfiltered web-crawled datasets. For instance Stable Diffusion may unexpectedly generate nudity, violence, images depicting self-harm, and otherwise offensive content. Safe Stable Diffusion is an extension of Stable Diffusion that drastically reduces this type of content.
|
| 16 |
+
|
| 17 |
+
The abstract from the paper is:
|
| 18 |
+
|
| 19 |
+
*Text-conditioned image generation models have recently achieved astonishing results in image quality and text alignment and are consequently employed in a fast-growing number of applications. Since they are highly data-driven, relying on billion-sized datasets randomly scraped from the internet, they also suffer, as we demonstrate, from degenerated and biased human behavior. In turn, they may even reinforce such biases. To help combat these undesired side effects, we present safe latent diffusion (SLD). Specifically, to measure the inappropriate degeneration due to unfiltered and imbalanced training sets, we establish a novel image generation test bed-inappropriate image prompts (I2P)-containing dedicated, real-world image-to-text prompts covering concepts such as nudity and violence. As our exhaustive empirical evaluation demonstrates, the introduced SLD removes and suppresses inappropriate image parts during the diffusion process, with no additional training required and no adverse effect on overall image quality or text alignment.*
|
| 20 |
+
|
| 21 |
+
## Tips
|
| 22 |
+
|
| 23 |
+
Use the `safety_concept` property of [`StableDiffusionPipelineSafe`] to check and edit the current safety concept:
|
| 24 |
+
|
| 25 |
+
```python
|
| 26 |
+
>>> from diffusers import StableDiffusionPipelineSafe
|
| 27 |
+
|
| 28 |
+
>>> pipeline = StableDiffusionPipelineSafe.from_pretrained("AIML-TUDA/stable-diffusion-safe")
|
| 29 |
+
>>> pipeline.safety_concept
|
| 30 |
+
'an image showing hate, harassment, violence, suffering, humiliation, harm, suicide, sexual, nudity, bodily fluids, blood, obscene gestures, illegal activity, drug use, theft, vandalism, weapons, child abuse, brutality, cruelty'
|
| 31 |
+
```
|
| 32 |
+
For each image generation the active concept is also contained in [`StableDiffusionSafePipelineOutput`].
|
| 33 |
+
|
| 34 |
+
There are 4 configurations (`SafetyConfig.WEAK`, `SafetyConfig.MEDIUM`, `SafetyConfig.STRONG`, and `SafetyConfig.MAX`) that can be applied:
|
| 35 |
+
|
| 36 |
+
```python
|
| 37 |
+
>>> from diffusers import StableDiffusionPipelineSafe
|
| 38 |
+
>>> from diffusers.pipelines.stable_diffusion_safe import SafetyConfig
|
| 39 |
+
|
| 40 |
+
>>> pipeline = StableDiffusionPipelineSafe.from_pretrained("AIML-TUDA/stable-diffusion-safe")
|
| 41 |
+
>>> prompt = "the four horsewomen of the apocalypse, painting by tom of finland, gaston bussiere, craig mullins, j. c. leyendecker"
|
| 42 |
+
>>> out = pipeline(prompt=prompt, **SafetyConfig.MAX)
|
| 43 |
+
```
|
| 44 |
+
|
| 45 |
+
<Tip>
|
| 46 |
+
|
| 47 |
+
Make sure to check out the Stable Diffusion [Tips](overview#tips) section to learn how to explore the tradeoff between scheduler speed and quality, and how to reuse pipeline components efficiently!
|
| 48 |
+
|
| 49 |
+
</Tip>
|
| 50 |
+
|
| 51 |
+
## StableDiffusionPipelineSafe
|
| 52 |
+
|
| 53 |
+
[[autodoc]] StableDiffusionPipelineSafe
|
| 54 |
+
- all
|
| 55 |
+
- __call__
|
| 56 |
+
|
| 57 |
+
## StableDiffusionSafePipelineOutput
|
| 58 |
+
|
| 59 |
+
[[autodoc]] pipelines.stable_diffusion_safe.StableDiffusionSafePipelineOutput
|
| 60 |
+
- all
|
| 61 |
+
- __call__
|
tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/stable_diffusion/stable_diffusion_xl.md
ADDED
|
@@ -0,0 +1,60 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Stable Diffusion XL
|
| 14 |
+
|
| 15 |
+
<div class="flex flex-wrap space-x-1">
|
| 16 |
+
<img alt="LoRA" src="https://img.shields.io/badge/LoRA-d8b4fe?style=flat"/>
|
| 17 |
+
<img alt="MPS" src="https://img.shields.io/badge/MPS-000000?style=flat&logo=apple&logoColor=white%22">
|
| 18 |
+
</div>
|
| 19 |
+
|
| 20 |
+
Stable Diffusion XL (SDXL) was proposed in [SDXL: Improving Latent Diffusion Models for High-Resolution Image Synthesis](https://huggingface.co/papers/2307.01952) by Dustin Podell, Zion English, Kyle Lacey, Andreas Blattmann, Tim Dockhorn, Jonas Müller, Joe Penna, and Robin Rombach.
|
| 21 |
+
|
| 22 |
+
The abstract from the paper is:
|
| 23 |
+
|
| 24 |
+
*We present SDXL, a latent diffusion model for text-to-image synthesis. Compared to previous versions of Stable Diffusion, SDXL leverages a three times larger UNet backbone: The increase of model parameters is mainly due to more attention blocks and a larger cross-attention context as SDXL uses a second text encoder. We design multiple novel conditioning schemes and train SDXL on multiple aspect ratios. We also introduce a refinement model which is used to improve the visual fidelity of samples generated by SDXL using a post-hoc image-to-image technique. We demonstrate that SDXL shows drastically improved performance compared the previous versions of Stable Diffusion and achieves results competitive with those of black-box state-of-the-art image generators.*
|
| 25 |
+
|
| 26 |
+
## Tips
|
| 27 |
+
|
| 28 |
+
- Using SDXL with a DPM++ scheduler for less than 50 steps is known to produce [visual artifacts](https://github.com/huggingface/diffusers/issues/5433) because the solver becomes numerically unstable. To fix this issue, take a look at this [PR](https://github.com/huggingface/diffusers/pull/5541) which recommends for ODE/SDE solvers:
|
| 29 |
+
- set `use_karras_sigmas=True` or `lu_lambdas=True` to improve image quality
|
| 30 |
+
- set `euler_at_final=True` if you're using a solver with uniform step sizes (DPM++2M or DPM++2M SDE)
|
| 31 |
+
- Most SDXL checkpoints work best with an image size of 1024x1024. Image sizes of 768x768 and 512x512 are also supported, but the results aren't as good. Anything below 512x512 is not recommended and likely won't be for default checkpoints like [stabilityai/stable-diffusion-xl-base-1.0](https://huggingface.co/stabilityai/stable-diffusion-xl-base-1.0).
|
| 32 |
+
- SDXL can pass a different prompt for each of the text encoders it was trained on. We can even pass different parts of the same prompt to the text encoders.
|
| 33 |
+
- SDXL output images can be improved by making use of a refiner model in an image-to-image setting.
|
| 34 |
+
- SDXL offers `negative_original_size`, `negative_crops_coords_top_left`, and `negative_target_size` to negatively condition the model on image resolution and cropping parameters.
|
| 35 |
+
|
| 36 |
+
<Tip>
|
| 37 |
+
|
| 38 |
+
To learn how to use SDXL for various tasks, how to optimize performance, and other usage examples, take a look at the [Stable Diffusion XL](../../../using-diffusers/sdxl) guide.
|
| 39 |
+
|
| 40 |
+
Check out the [Stability AI](https://huggingface.co/stabilityai) Hub organization for the official base and refiner model checkpoints!
|
| 41 |
+
|
| 42 |
+
</Tip>
|
| 43 |
+
|
| 44 |
+
## StableDiffusionXLPipeline
|
| 45 |
+
|
| 46 |
+
[[autodoc]] StableDiffusionXLPipeline
|
| 47 |
+
- all
|
| 48 |
+
- __call__
|
| 49 |
+
|
| 50 |
+
## StableDiffusionXLImg2ImgPipeline
|
| 51 |
+
|
| 52 |
+
[[autodoc]] StableDiffusionXLImg2ImgPipeline
|
| 53 |
+
- all
|
| 54 |
+
- __call__
|
| 55 |
+
|
| 56 |
+
## StableDiffusionXLInpaintPipeline
|
| 57 |
+
|
| 58 |
+
[[autodoc]] StableDiffusionXLInpaintPipeline
|
| 59 |
+
- all
|
| 60 |
+
- __call__
|
tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/stable_diffusion/svd.md
ADDED
|
@@ -0,0 +1,43 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Stable Video Diffusion
|
| 14 |
+
|
| 15 |
+
Stable Video Diffusion was proposed in [Stable Video Diffusion: Scaling Latent Video Diffusion Models to Large Datasets](https://hf.co/papers/2311.15127) by Andreas Blattmann, Tim Dockhorn, Sumith Kulal, Daniel Mendelevitch, Maciej Kilian, Dominik Lorenz, Yam Levi, Zion English, Vikram Voleti, Adam Letts, Varun Jampani, Robin Rombach.
|
| 16 |
+
|
| 17 |
+
The abstract from the paper is:
|
| 18 |
+
|
| 19 |
+
*We present Stable Video Diffusion - a latent video diffusion model for high-resolution, state-of-the-art text-to-video and image-to-video generation. Recently, latent diffusion models trained for 2D image synthesis have been turned into generative video models by inserting temporal layers and finetuning them on small, high-quality video datasets. However, training methods in the literature vary widely, and the field has yet to agree on a unified strategy for curating video data. In this paper, we identify and evaluate three different stages for successful training of video LDMs: text-to-image pretraining, video pretraining, and high-quality video finetuning. Furthermore, we demonstrate the necessity of a well-curated pretraining dataset for generating high-quality videos and present a systematic curation process to train a strong base model, including captioning and filtering strategies. We then explore the impact of finetuning our base model on high-quality data and train a text-to-video model that is competitive with closed-source video generation. We also show that our base model provides a powerful motion representation for downstream tasks such as image-to-video generation and adaptability to camera motion-specific LoRA modules. Finally, we demonstrate that our model provides a strong multi-view 3D-prior and can serve as a base to finetune a multi-view diffusion model that jointly generates multiple views of objects in a feedforward fashion, outperforming image-based methods at a fraction of their compute budget. We release code and model weights at this https URL.*
|
| 20 |
+
|
| 21 |
+
<Tip>
|
| 22 |
+
|
| 23 |
+
To learn how to use Stable Video Diffusion, take a look at the [Stable Video Diffusion](../../../using-diffusers/svd) guide.
|
| 24 |
+
|
| 25 |
+
<br>
|
| 26 |
+
|
| 27 |
+
Check out the [Stability AI](https://huggingface.co/stabilityai) Hub organization for the [base](https://huggingface.co/stabilityai/stable-video-diffusion-img2vid) and [extended frame](https://huggingface.co/stabilityai/stable-video-diffusion-img2vid-xt) checkpoints!
|
| 28 |
+
|
| 29 |
+
</Tip>
|
| 30 |
+
|
| 31 |
+
## Tips
|
| 32 |
+
|
| 33 |
+
Video generation is memory-intensive and one way to reduce your memory usage is to set `enable_forward_chunking` on the pipeline's UNet so you don't run the entire feedforward layer at once. Breaking it up into chunks in a loop is more efficient.
|
| 34 |
+
|
| 35 |
+
Check out the [Text or image-to-video](text-img2vid) guide for more details about how certain parameters can affect video generation and how to optimize inference by reducing memory usage.
|
| 36 |
+
|
| 37 |
+
## StableVideoDiffusionPipeline
|
| 38 |
+
|
| 39 |
+
[[autodoc]] StableVideoDiffusionPipeline
|
| 40 |
+
|
| 41 |
+
## StableVideoDiffusionPipelineOutput
|
| 42 |
+
|
| 43 |
+
[[autodoc]] pipelines.stable_video_diffusion.StableVideoDiffusionPipelineOutput
|
tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/stable_diffusion/text2img.md
ADDED
|
@@ -0,0 +1,63 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Text-to-image
|
| 14 |
+
|
| 15 |
+
<div class="flex flex-wrap space-x-1">
|
| 16 |
+
<img alt="LoRA" src="https://img.shields.io/badge/LoRA-d8b4fe?style=flat"/>
|
| 17 |
+
</div>
|
| 18 |
+
|
| 19 |
+
The Stable Diffusion model was created by researchers and engineers from [CompVis](https://github.com/CompVis), [Stability AI](https://stability.ai/), [Runway](https://github.com/runwayml), and [LAION](https://laion.ai/). The [`StableDiffusionPipeline`] is capable of generating photorealistic images given any text input. It's trained on 512x512 images from a subset of the LAION-5B dataset. This model uses a frozen CLIP ViT-L/14 text encoder to condition the model on text prompts. With its 860M UNet and 123M text encoder, the model is relatively lightweight and can run on consumer GPUs. Latent diffusion is the research on top of which Stable Diffusion was built. It was proposed in [High-Resolution Image Synthesis with Latent Diffusion Models](https://huggingface.co/papers/2112.10752) by Robin Rombach, Andreas Blattmann, Dominik Lorenz, Patrick Esser, Björn Ommer.
|
| 20 |
+
|
| 21 |
+
The abstract from the paper is:
|
| 22 |
+
|
| 23 |
+
*By decomposing the image formation process into a sequential application of denoising autoencoders, diffusion models (DMs) achieve state-of-the-art synthesis results on image data and beyond. Additionally, their formulation allows for a guiding mechanism to control the image generation process without retraining. However, since these models typically operate directly in pixel space, optimization of powerful DMs often consumes hundreds of GPU days and inference is expensive due to sequential evaluations. To enable DM training on limited computational resources while retaining their quality and flexibility, we apply them in the latent space of powerful pretrained autoencoders. In contrast to previous work, training diffusion models on such a representation allows for the first time to reach a near-optimal point between complexity reduction and detail preservation, greatly boosting visual fidelity. By introducing cross-attention layers into the model architecture, we turn diffusion models into powerful and flexible generators for general conditioning inputs such as text or bounding boxes and high-resolution synthesis becomes possible in a convolutional manner. Our latent diffusion models (LDMs) achieve a new state of the art for image inpainting and highly competitive performance on various tasks, including unconditional image generation, semantic scene synthesis, and super-resolution, while significantly reducing computational requirements compared to pixel-based DMs. Code is available at https://github.com/CompVis/latent-diffusion.*
|
| 24 |
+
|
| 25 |
+
<Tip>
|
| 26 |
+
|
| 27 |
+
Make sure to check out the Stable Diffusion [Tips](overview#tips) section to learn how to explore the tradeoff between scheduler speed and quality, and how to reuse pipeline components efficiently!
|
| 28 |
+
|
| 29 |
+
If you're interested in using one of the official checkpoints for a task, explore the [CompVis](https://huggingface.co/CompVis), [Runway](https://huggingface.co/runwayml), and [Stability AI](https://huggingface.co/stabilityai) Hub organizations!
|
| 30 |
+
|
| 31 |
+
</Tip>
|
| 32 |
+
|
| 33 |
+
## StableDiffusionPipeline
|
| 34 |
+
|
| 35 |
+
[[autodoc]] StableDiffusionPipeline
|
| 36 |
+
- all
|
| 37 |
+
- __call__
|
| 38 |
+
- enable_attention_slicing
|
| 39 |
+
- disable_attention_slicing
|
| 40 |
+
- enable_vae_slicing
|
| 41 |
+
- disable_vae_slicing
|
| 42 |
+
- enable_xformers_memory_efficient_attention
|
| 43 |
+
- disable_xformers_memory_efficient_attention
|
| 44 |
+
- enable_vae_tiling
|
| 45 |
+
- disable_vae_tiling
|
| 46 |
+
- load_textual_inversion
|
| 47 |
+
- from_single_file
|
| 48 |
+
- load_lora_weights
|
| 49 |
+
- save_lora_weights
|
| 50 |
+
|
| 51 |
+
## StableDiffusionPipelineOutput
|
| 52 |
+
|
| 53 |
+
[[autodoc]] pipelines.stable_diffusion.StableDiffusionPipelineOutput
|
| 54 |
+
|
| 55 |
+
## FlaxStableDiffusionPipeline
|
| 56 |
+
|
| 57 |
+
[[autodoc]] FlaxStableDiffusionPipeline
|
| 58 |
+
- all
|
| 59 |
+
- __call__
|
| 60 |
+
|
| 61 |
+
## FlaxStableDiffusionPipelineOutput
|
| 62 |
+
|
| 63 |
+
[[autodoc]] pipelines.stable_diffusion.FlaxStableDiffusionPipelineOutput
|
tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/stable_diffusion/upscale.md
ADDED
|
@@ -0,0 +1,41 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Super-resolution
|
| 14 |
+
|
| 15 |
+
<div class="flex flex-wrap space-x-1">
|
| 16 |
+
<img alt="LoRA" src="https://img.shields.io/badge/LoRA-d8b4fe?style=flat"/>
|
| 17 |
+
</div>
|
| 18 |
+
|
| 19 |
+
The Stable Diffusion upscaler diffusion model was created by the researchers and engineers from [CompVis](https://github.com/CompVis), [Stability AI](https://stability.ai/), and [LAION](https://laion.ai/). It is used to enhance the resolution of input images by a factor of 4.
|
| 20 |
+
|
| 21 |
+
<Tip>
|
| 22 |
+
|
| 23 |
+
Make sure to check out the Stable Diffusion [Tips](overview#tips) section to learn how to explore the tradeoff between scheduler speed and quality, and how to reuse pipeline components efficiently!
|
| 24 |
+
|
| 25 |
+
If you're interested in using one of the official checkpoints for a task, explore the [CompVis](https://huggingface.co/CompVis), [Runway](https://huggingface.co/runwayml), and [Stability AI](https://huggingface.co/stabilityai) Hub organizations!
|
| 26 |
+
|
| 27 |
+
</Tip>
|
| 28 |
+
|
| 29 |
+
## StableDiffusionUpscalePipeline
|
| 30 |
+
|
| 31 |
+
[[autodoc]] StableDiffusionUpscalePipeline
|
| 32 |
+
- all
|
| 33 |
+
- __call__
|
| 34 |
+
- enable_attention_slicing
|
| 35 |
+
- disable_attention_slicing
|
| 36 |
+
- enable_xformers_memory_efficient_attention
|
| 37 |
+
- disable_xformers_memory_efficient_attention
|
| 38 |
+
|
| 39 |
+
## StableDiffusionPipelineOutput
|
| 40 |
+
|
| 41 |
+
[[autodoc]] pipelines.stable_diffusion.StableDiffusionPipelineOutput
|
tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/stable_unclip.md
ADDED
|
@@ -0,0 +1,133 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Stable unCLIP
|
| 14 |
+
|
| 15 |
+
<div class="flex flex-wrap space-x-1">
|
| 16 |
+
<img alt="LoRA" src="https://img.shields.io/badge/LoRA-d8b4fe?style=flat"/>
|
| 17 |
+
</div>
|
| 18 |
+
|
| 19 |
+
Stable unCLIP checkpoints are finetuned from [Stable Diffusion 2.1](./stable_diffusion/stable_diffusion_2) checkpoints to condition on CLIP image embeddings.
|
| 20 |
+
Stable unCLIP still conditions on text embeddings. Given the two separate conditionings, stable unCLIP can be used
|
| 21 |
+
for text guided image variation. When combined with an unCLIP prior, it can also be used for full text to image generation.
|
| 22 |
+
|
| 23 |
+
The abstract from the paper is:
|
| 24 |
+
|
| 25 |
+
*Contrastive models like CLIP have been shown to learn robust representations of images that capture both semantics and style. To leverage these representations for image generation, we propose a two-stage model: a prior that generates a CLIP image embedding given a text caption, and a decoder that generates an image conditioned on the image embedding. We show that explicitly generating image representations improves image diversity with minimal loss in photorealism and caption similarity. Our decoders conditioned on image representations can also produce variations of an image that preserve both its semantics and style, while varying the non-essential details absent from the image representation. Moreover, the joint embedding space of CLIP enables language-guided image manipulations in a zero-shot fashion. We use diffusion models for the decoder and experiment with both autoregressive and diffusion models for the prior, finding that the latter are computationally more efficient and produce higher-quality samples.*
|
| 26 |
+
|
| 27 |
+
## Tips
|
| 28 |
+
|
| 29 |
+
Stable unCLIP takes `noise_level` as input during inference which determines how much noise is added to the image embeddings. A higher `noise_level` increases variation in the final un-noised images. By default, we do not add any additional noise to the image embeddings (`noise_level = 0`).
|
| 30 |
+
|
| 31 |
+
### Text-to-Image Generation
|
| 32 |
+
Stable unCLIP can be leveraged for text-to-image generation by pipelining it with the prior model of KakaoBrain's open source DALL-E 2 replication [Karlo](https://huggingface.co/kakaobrain/karlo-v1-alpha):
|
| 33 |
+
|
| 34 |
+
```python
|
| 35 |
+
import torch
|
| 36 |
+
from diffusers import UnCLIPScheduler, DDPMScheduler, StableUnCLIPPipeline
|
| 37 |
+
from diffusers.models import PriorTransformer
|
| 38 |
+
from transformers import CLIPTokenizer, CLIPTextModelWithProjection
|
| 39 |
+
|
| 40 |
+
prior_model_id = "kakaobrain/karlo-v1-alpha"
|
| 41 |
+
data_type = torch.float16
|
| 42 |
+
prior = PriorTransformer.from_pretrained(prior_model_id, subfolder="prior", torch_dtype=data_type)
|
| 43 |
+
|
| 44 |
+
prior_text_model_id = "openai/clip-vit-large-patch14"
|
| 45 |
+
prior_tokenizer = CLIPTokenizer.from_pretrained(prior_text_model_id)
|
| 46 |
+
prior_text_model = CLIPTextModelWithProjection.from_pretrained(prior_text_model_id, torch_dtype=data_type)
|
| 47 |
+
prior_scheduler = UnCLIPScheduler.from_pretrained(prior_model_id, subfolder="prior_scheduler")
|
| 48 |
+
prior_scheduler = DDPMScheduler.from_config(prior_scheduler.config)
|
| 49 |
+
|
| 50 |
+
stable_unclip_model_id = "stabilityai/stable-diffusion-2-1-unclip-small"
|
| 51 |
+
|
| 52 |
+
pipe = StableUnCLIPPipeline.from_pretrained(
|
| 53 |
+
stable_unclip_model_id,
|
| 54 |
+
torch_dtype=data_type,
|
| 55 |
+
variant="fp16",
|
| 56 |
+
prior_tokenizer=prior_tokenizer,
|
| 57 |
+
prior_text_encoder=prior_text_model,
|
| 58 |
+
prior=prior,
|
| 59 |
+
prior_scheduler=prior_scheduler,
|
| 60 |
+
)
|
| 61 |
+
|
| 62 |
+
pipe = pipe.to("cuda")
|
| 63 |
+
wave_prompt = "dramatic wave, the Oceans roar, Strong wave spiral across the oceans as the waves unfurl into roaring crests; perfect wave form; perfect wave shape; dramatic wave shape; wave shape unbelievable; wave; wave shape spectacular"
|
| 64 |
+
|
| 65 |
+
image = pipe(prompt=wave_prompt).images[0]
|
| 66 |
+
image
|
| 67 |
+
```
|
| 68 |
+
<Tip warning={true}>
|
| 69 |
+
|
| 70 |
+
For text-to-image we use `stabilityai/stable-diffusion-2-1-unclip-small` as it was trained on CLIP ViT-L/14 embedding, the same as the Karlo model prior. [stabilityai/stable-diffusion-2-1-unclip](https://hf.co/stabilityai/stable-diffusion-2-1-unclip) was trained on OpenCLIP ViT-H, so we don't recommend its use.
|
| 71 |
+
|
| 72 |
+
</Tip>
|
| 73 |
+
|
| 74 |
+
### Text guided Image-to-Image Variation
|
| 75 |
+
|
| 76 |
+
```python
|
| 77 |
+
from diffusers import StableUnCLIPImg2ImgPipeline
|
| 78 |
+
from diffusers.utils import load_image
|
| 79 |
+
import torch
|
| 80 |
+
|
| 81 |
+
pipe = StableUnCLIPImg2ImgPipeline.from_pretrained(
|
| 82 |
+
"stabilityai/stable-diffusion-2-1-unclip", torch_dtype=torch.float16, variation="fp16"
|
| 83 |
+
)
|
| 84 |
+
pipe = pipe.to("cuda")
|
| 85 |
+
|
| 86 |
+
url = "https://huggingface.co/datasets/hf-internal-testing/diffusers-images/resolve/main/stable_unclip/tarsila_do_amaral.png"
|
| 87 |
+
init_image = load_image(url)
|
| 88 |
+
|
| 89 |
+
images = pipe(init_image).images
|
| 90 |
+
images[0].save("variation_image.png")
|
| 91 |
+
```
|
| 92 |
+
|
| 93 |
+
Optionally, you can also pass a prompt to `pipe` such as:
|
| 94 |
+
|
| 95 |
+
```python
|
| 96 |
+
prompt = "A fantasy landscape, trending on artstation"
|
| 97 |
+
|
| 98 |
+
image = pipe(init_image, prompt=prompt).images[0]
|
| 99 |
+
image
|
| 100 |
+
```
|
| 101 |
+
|
| 102 |
+
<Tip>
|
| 103 |
+
|
| 104 |
+
Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines.
|
| 105 |
+
|
| 106 |
+
</Tip>
|
| 107 |
+
|
| 108 |
+
## StableUnCLIPPipeline
|
| 109 |
+
|
| 110 |
+
[[autodoc]] StableUnCLIPPipeline
|
| 111 |
+
- all
|
| 112 |
+
- __call__
|
| 113 |
+
- enable_attention_slicing
|
| 114 |
+
- disable_attention_slicing
|
| 115 |
+
- enable_vae_slicing
|
| 116 |
+
- disable_vae_slicing
|
| 117 |
+
- enable_xformers_memory_efficient_attention
|
| 118 |
+
- disable_xformers_memory_efficient_attention
|
| 119 |
+
|
| 120 |
+
## StableUnCLIPImg2ImgPipeline
|
| 121 |
+
|
| 122 |
+
[[autodoc]] StableUnCLIPImg2ImgPipeline
|
| 123 |
+
- all
|
| 124 |
+
- __call__
|
| 125 |
+
- enable_attention_slicing
|
| 126 |
+
- disable_attention_slicing
|
| 127 |
+
- enable_vae_slicing
|
| 128 |
+
- disable_vae_slicing
|
| 129 |
+
- enable_xformers_memory_efficient_attention
|
| 130 |
+
- disable_xformers_memory_efficient_attention
|
| 131 |
+
|
| 132 |
+
## ImagePipelineOutput
|
| 133 |
+
[[autodoc]] pipelines.ImagePipelineOutput
|
tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/text_to_video.md
ADDED
|
@@ -0,0 +1,197 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
<Tip warning={true}>
|
| 14 |
+
|
| 15 |
+
🧪 This pipeline is for research purposes only.
|
| 16 |
+
|
| 17 |
+
</Tip>
|
| 18 |
+
|
| 19 |
+
# Text-to-video
|
| 20 |
+
|
| 21 |
+
<div class="flex flex-wrap space-x-1">
|
| 22 |
+
<img alt="LoRA" src="https://img.shields.io/badge/LoRA-d8b4fe?style=flat"/>
|
| 23 |
+
</div>
|
| 24 |
+
|
| 25 |
+
[ModelScope Text-to-Video Technical Report](https://huggingface.co/papers/2308.06571) is by Jiuniu Wang, Hangjie Yuan, Dayou Chen, Yingya Zhang, Xiang Wang, Shiwei Zhang.
|
| 26 |
+
|
| 27 |
+
The abstract from the paper is:
|
| 28 |
+
|
| 29 |
+
*This paper introduces ModelScopeT2V, a text-to-video synthesis model that evolves from a text-to-image synthesis model (i.e., Stable Diffusion). ModelScopeT2V incorporates spatio-temporal blocks to ensure consistent frame generation and smooth movement transitions. The model could adapt to varying frame numbers during training and inference, rendering it suitable for both image-text and video-text datasets. ModelScopeT2V brings together three components (i.e., VQGAN, a text encoder, and a denoising UNet), totally comprising 1.7 billion parameters, in which 0.5 billion parameters are dedicated to temporal capabilities. The model demonstrates superior performance over state-of-the-art methods across three evaluation metrics. The code and an online demo are available at https://modelscope.cn/models/damo/text-to-video-synthesis/summary.*
|
| 30 |
+
|
| 31 |
+
You can find additional information about Text-to-Video on the [project page](https://modelscope.cn/models/damo/text-to-video-synthesis/summary), [original codebase](https://github.com/modelscope/modelscope/), and try it out in a [demo](https://huggingface.co/spaces/damo-vilab/modelscope-text-to-video-synthesis). Official checkpoints can be found at [damo-vilab](https://huggingface.co/damo-vilab) and [cerspense](https://huggingface.co/cerspense).
|
| 32 |
+
|
| 33 |
+
## Usage example
|
| 34 |
+
|
| 35 |
+
### `text-to-video-ms-1.7b`
|
| 36 |
+
|
| 37 |
+
Let's start by generating a short video with the default length of 16 frames (2s at 8 fps):
|
| 38 |
+
|
| 39 |
+
```python
|
| 40 |
+
import torch
|
| 41 |
+
from diffusers import DiffusionPipeline
|
| 42 |
+
from diffusers.utils import export_to_video
|
| 43 |
+
|
| 44 |
+
pipe = DiffusionPipeline.from_pretrained("damo-vilab/text-to-video-ms-1.7b", torch_dtype=torch.float16, variant="fp16")
|
| 45 |
+
pipe = pipe.to("cuda")
|
| 46 |
+
|
| 47 |
+
prompt = "Spiderman is surfing"
|
| 48 |
+
video_frames = pipe(prompt).frames[0]
|
| 49 |
+
video_path = export_to_video(video_frames)
|
| 50 |
+
video_path
|
| 51 |
+
```
|
| 52 |
+
|
| 53 |
+
Diffusers supports different optimization techniques to improve the latency
|
| 54 |
+
and memory footprint of a pipeline. Since videos are often more memory-heavy than images,
|
| 55 |
+
we can enable CPU offloading and VAE slicing to keep the memory footprint at bay.
|
| 56 |
+
|
| 57 |
+
Let's generate a video of 8 seconds (64 frames) on the same GPU using CPU offloading and VAE slicing:
|
| 58 |
+
|
| 59 |
+
```python
|
| 60 |
+
import torch
|
| 61 |
+
from diffusers import DiffusionPipeline
|
| 62 |
+
from diffusers.utils import export_to_video
|
| 63 |
+
|
| 64 |
+
pipe = DiffusionPipeline.from_pretrained("damo-vilab/text-to-video-ms-1.7b", torch_dtype=torch.float16, variant="fp16")
|
| 65 |
+
pipe.enable_model_cpu_offload()
|
| 66 |
+
|
| 67 |
+
# memory optimization
|
| 68 |
+
pipe.enable_vae_slicing()
|
| 69 |
+
|
| 70 |
+
prompt = "Darth Vader surfing a wave"
|
| 71 |
+
video_frames = pipe(prompt, num_frames=64).frames[0]
|
| 72 |
+
video_path = export_to_video(video_frames)
|
| 73 |
+
video_path
|
| 74 |
+
```
|
| 75 |
+
|
| 76 |
+
It just takes **7 GBs of GPU memory** to generate the 64 video frames using PyTorch 2.0, "fp16" precision and the techniques mentioned above.
|
| 77 |
+
|
| 78 |
+
We can also use a different scheduler easily, using the same method we'd use for Stable Diffusion:
|
| 79 |
+
|
| 80 |
+
```python
|
| 81 |
+
import torch
|
| 82 |
+
from diffusers import DiffusionPipeline, DPMSolverMultistepScheduler
|
| 83 |
+
from diffusers.utils import export_to_video
|
| 84 |
+
|
| 85 |
+
pipe = DiffusionPipeline.from_pretrained("damo-vilab/text-to-video-ms-1.7b", torch_dtype=torch.float16, variant="fp16")
|
| 86 |
+
pipe.scheduler = DPMSolverMultistepScheduler.from_config(pipe.scheduler.config)
|
| 87 |
+
pipe.enable_model_cpu_offload()
|
| 88 |
+
|
| 89 |
+
prompt = "Spiderman is surfing"
|
| 90 |
+
video_frames = pipe(prompt, num_inference_steps=25).frames[0]
|
| 91 |
+
video_path = export_to_video(video_frames)
|
| 92 |
+
video_path
|
| 93 |
+
```
|
| 94 |
+
|
| 95 |
+
Here are some sample outputs:
|
| 96 |
+
|
| 97 |
+
<table>
|
| 98 |
+
<tr>
|
| 99 |
+
<td><center>
|
| 100 |
+
An astronaut riding a horse.
|
| 101 |
+
<br>
|
| 102 |
+
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/astr.gif"
|
| 103 |
+
alt="An astronaut riding a horse."
|
| 104 |
+
style="width: 300px;" />
|
| 105 |
+
</center></td>
|
| 106 |
+
<td ><center>
|
| 107 |
+
Darth vader surfing in waves.
|
| 108 |
+
<br>
|
| 109 |
+
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/vader.gif"
|
| 110 |
+
alt="Darth vader surfing in waves."
|
| 111 |
+
style="width: 300px;" />
|
| 112 |
+
</center></td>
|
| 113 |
+
</tr>
|
| 114 |
+
</table>
|
| 115 |
+
|
| 116 |
+
### `cerspense/zeroscope_v2_576w` & `cerspense/zeroscope_v2_XL`
|
| 117 |
+
|
| 118 |
+
Zeroscope are watermark-free model and have been trained on specific sizes such as `576x320` and `1024x576`.
|
| 119 |
+
One should first generate a video using the lower resolution checkpoint [`cerspense/zeroscope_v2_576w`](https://huggingface.co/cerspense/zeroscope_v2_576w) with [`TextToVideoSDPipeline`],
|
| 120 |
+
which can then be upscaled using [`VideoToVideoSDPipeline`] and [`cerspense/zeroscope_v2_XL`](https://huggingface.co/cerspense/zeroscope_v2_XL).
|
| 121 |
+
|
| 122 |
+
|
| 123 |
+
```py
|
| 124 |
+
import torch
|
| 125 |
+
from diffusers import DiffusionPipeline, DPMSolverMultistepScheduler
|
| 126 |
+
from diffusers.utils import export_to_video
|
| 127 |
+
from PIL import Image
|
| 128 |
+
|
| 129 |
+
pipe = DiffusionPipeline.from_pretrained("cerspense/zeroscope_v2_576w", torch_dtype=torch.float16)
|
| 130 |
+
pipe.enable_model_cpu_offload()
|
| 131 |
+
|
| 132 |
+
# memory optimization
|
| 133 |
+
pipe.unet.enable_forward_chunking(chunk_size=1, dim=1)
|
| 134 |
+
pipe.enable_vae_slicing()
|
| 135 |
+
|
| 136 |
+
prompt = "Darth Vader surfing a wave"
|
| 137 |
+
video_frames = pipe(prompt, num_frames=24).frames[0]
|
| 138 |
+
video_path = export_to_video(video_frames)
|
| 139 |
+
video_path
|
| 140 |
+
```
|
| 141 |
+
|
| 142 |
+
Now the video can be upscaled:
|
| 143 |
+
|
| 144 |
+
```py
|
| 145 |
+
pipe = DiffusionPipeline.from_pretrained("cerspense/zeroscope_v2_XL", torch_dtype=torch.float16)
|
| 146 |
+
pipe.scheduler = DPMSolverMultistepScheduler.from_config(pipe.scheduler.config)
|
| 147 |
+
pipe.enable_model_cpu_offload()
|
| 148 |
+
|
| 149 |
+
# memory optimization
|
| 150 |
+
pipe.unet.enable_forward_chunking(chunk_size=1, dim=1)
|
| 151 |
+
pipe.enable_vae_slicing()
|
| 152 |
+
|
| 153 |
+
video = [Image.fromarray(frame).resize((1024, 576)) for frame in video_frames]
|
| 154 |
+
|
| 155 |
+
video_frames = pipe(prompt, video=video, strength=0.6).frames[0]
|
| 156 |
+
video_path = export_to_video(video_frames)
|
| 157 |
+
video_path
|
| 158 |
+
```
|
| 159 |
+
|
| 160 |
+
Here are some sample outputs:
|
| 161 |
+
|
| 162 |
+
<table>
|
| 163 |
+
<tr>
|
| 164 |
+
<td ><center>
|
| 165 |
+
Darth vader surfing in waves.
|
| 166 |
+
<br>
|
| 167 |
+
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/darthvader_cerpense.gif"
|
| 168 |
+
alt="Darth vader surfing in waves."
|
| 169 |
+
style="width: 576px;" />
|
| 170 |
+
</center></td>
|
| 171 |
+
</tr>
|
| 172 |
+
</table>
|
| 173 |
+
|
| 174 |
+
## Tips
|
| 175 |
+
|
| 176 |
+
Video generation is memory-intensive and one way to reduce your memory usage is to set `enable_forward_chunking` on the pipeline's UNet so you don't run the entire feedforward layer at once. Breaking it up into chunks in a loop is more efficient.
|
| 177 |
+
|
| 178 |
+
Check out the [Text or image-to-video](text-img2vid) guide for more details about how certain parameters can affect video generation and how to optimize inference by reducing memory usage.
|
| 179 |
+
|
| 180 |
+
<Tip>
|
| 181 |
+
|
| 182 |
+
Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines.
|
| 183 |
+
|
| 184 |
+
</Tip>
|
| 185 |
+
|
| 186 |
+
## TextToVideoSDPipeline
|
| 187 |
+
[[autodoc]] TextToVideoSDPipeline
|
| 188 |
+
- all
|
| 189 |
+
- __call__
|
| 190 |
+
|
| 191 |
+
## VideoToVideoSDPipeline
|
| 192 |
+
[[autodoc]] VideoToVideoSDPipeline
|
| 193 |
+
- all
|
| 194 |
+
- __call__
|
| 195 |
+
|
| 196 |
+
## TextToVideoSDPipelineOutput
|
| 197 |
+
[[autodoc]] pipelines.text_to_video_synthesis.TextToVideoSDPipelineOutput
|
tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/text_to_video_zero.md
ADDED
|
@@ -0,0 +1,306 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Text2Video-Zero
|
| 14 |
+
|
| 15 |
+
<div class="flex flex-wrap space-x-1">
|
| 16 |
+
<img alt="LoRA" src="https://img.shields.io/badge/LoRA-d8b4fe?style=flat"/>
|
| 17 |
+
</div>
|
| 18 |
+
|
| 19 |
+
[Text2Video-Zero: Text-to-Image Diffusion Models are Zero-Shot Video Generators](https://huggingface.co/papers/2303.13439) is by Levon Khachatryan, Andranik Movsisyan, Vahram Tadevosyan, Roberto Henschel, [Zhangyang Wang](https://www.ece.utexas.edu/people/faculty/atlas-wang), Shant Navasardyan, [Humphrey Shi](https://www.humphreyshi.com).
|
| 20 |
+
|
| 21 |
+
Text2Video-Zero enables zero-shot video generation using either:
|
| 22 |
+
1. A textual prompt
|
| 23 |
+
2. A prompt combined with guidance from poses or edges
|
| 24 |
+
3. Video Instruct-Pix2Pix (instruction-guided video editing)
|
| 25 |
+
|
| 26 |
+
Results are temporally consistent and closely follow the guidance and textual prompts.
|
| 27 |
+
|
| 28 |
+
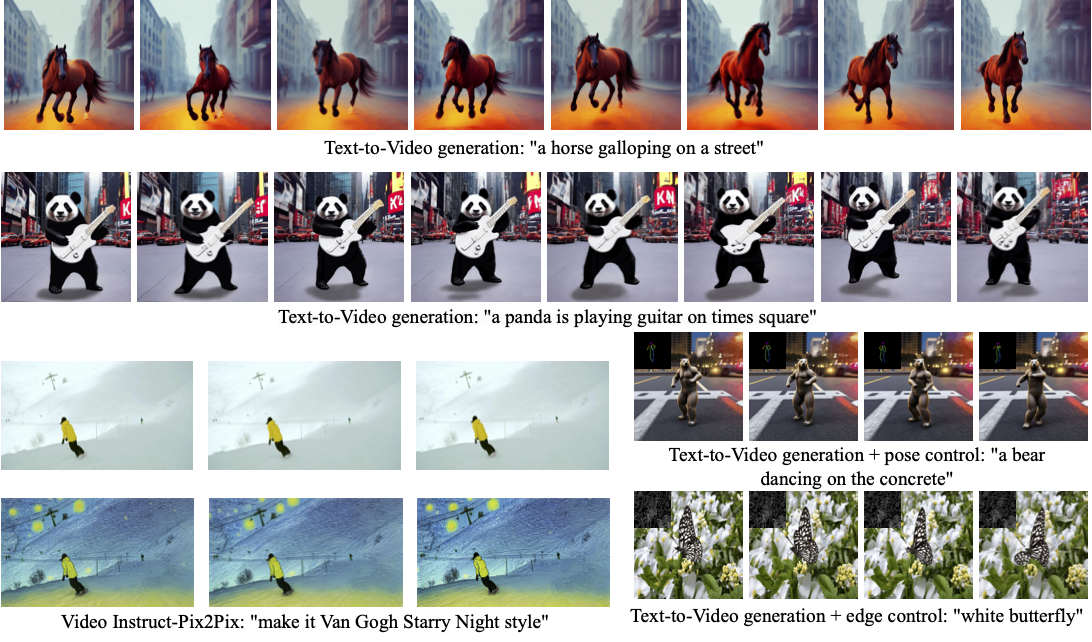
|
| 29 |
+
|
| 30 |
+
The abstract from the paper is:
|
| 31 |
+
|
| 32 |
+
*Recent text-to-video generation approaches rely on computationally heavy training and require large-scale video datasets. In this paper, we introduce a new task of zero-shot text-to-video generation and propose a low-cost approach (without any training or optimization) by leveraging the power of existing text-to-image synthesis methods (e.g., Stable Diffusion), making them suitable for the video domain.
|
| 33 |
+
Our key modifications include (i) enriching the latent codes of the generated frames with motion dynamics to keep the global scene and the background time consistent; and (ii) reprogramming frame-level self-attention using a new cross-frame attention of each frame on the first frame, to preserve the context, appearance, and identity of the foreground object.
|
| 34 |
+
Experiments show that this leads to low overhead, yet high-quality and remarkably consistent video generation. Moreover, our approach is not limited to text-to-video synthesis but is also applicable to other tasks such as conditional and content-specialized video generation, and Video Instruct-Pix2Pix, i.e., instruction-guided video editing.
|
| 35 |
+
As experiments show, our method performs comparably or sometimes better than recent approaches, despite not being trained on additional video data.*
|
| 36 |
+
|
| 37 |
+
You can find additional information about Text2Video-Zero on the [project page](https://text2video-zero.github.io/), [paper](https://huggingface.co/papers/2303.13439), and [original codebase](https://github.com/Picsart-AI-Research/Text2Video-Zero).
|
| 38 |
+
|
| 39 |
+
## Usage example
|
| 40 |
+
|
| 41 |
+
### Text-To-Video
|
| 42 |
+
|
| 43 |
+
To generate a video from prompt, run the following Python code:
|
| 44 |
+
```python
|
| 45 |
+
import torch
|
| 46 |
+
from diffusers import TextToVideoZeroPipeline
|
| 47 |
+
import imageio
|
| 48 |
+
|
| 49 |
+
model_id = "stable-diffusion-v1-5/stable-diffusion-v1-5"
|
| 50 |
+
pipe = TextToVideoZeroPipeline.from_pretrained(model_id, torch_dtype=torch.float16).to("cuda")
|
| 51 |
+
|
| 52 |
+
prompt = "A panda is playing guitar on times square"
|
| 53 |
+
result = pipe(prompt=prompt).images
|
| 54 |
+
result = [(r * 255).astype("uint8") for r in result]
|
| 55 |
+
imageio.mimsave("video.mp4", result, fps=4)
|
| 56 |
+
```
|
| 57 |
+
You can change these parameters in the pipeline call:
|
| 58 |
+
* Motion field strength (see the [paper](https://huggingface.co/papers/2303.13439), Sect. 3.3.1):
|
| 59 |
+
* `motion_field_strength_x` and `motion_field_strength_y`. Default: `motion_field_strength_x=12`, `motion_field_strength_y=12`
|
| 60 |
+
* `T` and `T'` (see the [paper](https://huggingface.co/papers/2303.13439), Sect. 3.3.1)
|
| 61 |
+
* `t0` and `t1` in the range `{0, ..., num_inference_steps}`. Default: `t0=45`, `t1=48`
|
| 62 |
+
* Video length:
|
| 63 |
+
* `video_length`, the number of frames video_length to be generated. Default: `video_length=8`
|
| 64 |
+
|
| 65 |
+
We can also generate longer videos by doing the processing in a chunk-by-chunk manner:
|
| 66 |
+
```python
|
| 67 |
+
import torch
|
| 68 |
+
from diffusers import TextToVideoZeroPipeline
|
| 69 |
+
import numpy as np
|
| 70 |
+
|
| 71 |
+
model_id = "stable-diffusion-v1-5/stable-diffusion-v1-5"
|
| 72 |
+
pipe = TextToVideoZeroPipeline.from_pretrained(model_id, torch_dtype=torch.float16).to("cuda")
|
| 73 |
+
seed = 0
|
| 74 |
+
video_length = 24 #24 ÷ 4fps = 6 seconds
|
| 75 |
+
chunk_size = 8
|
| 76 |
+
prompt = "A panda is playing guitar on times square"
|
| 77 |
+
|
| 78 |
+
# Generate the video chunk-by-chunk
|
| 79 |
+
result = []
|
| 80 |
+
chunk_ids = np.arange(0, video_length, chunk_size - 1)
|
| 81 |
+
generator = torch.Generator(device="cuda")
|
| 82 |
+
for i in range(len(chunk_ids)):
|
| 83 |
+
print(f"Processing chunk {i + 1} / {len(chunk_ids)}")
|
| 84 |
+
ch_start = chunk_ids[i]
|
| 85 |
+
ch_end = video_length if i == len(chunk_ids) - 1 else chunk_ids[i + 1]
|
| 86 |
+
# Attach the first frame for Cross Frame Attention
|
| 87 |
+
frame_ids = [0] + list(range(ch_start, ch_end))
|
| 88 |
+
# Fix the seed for the temporal consistency
|
| 89 |
+
generator.manual_seed(seed)
|
| 90 |
+
output = pipe(prompt=prompt, video_length=len(frame_ids), generator=generator, frame_ids=frame_ids)
|
| 91 |
+
result.append(output.images[1:])
|
| 92 |
+
|
| 93 |
+
# Concatenate chunks and save
|
| 94 |
+
result = np.concatenate(result)
|
| 95 |
+
result = [(r * 255).astype("uint8") for r in result]
|
| 96 |
+
imageio.mimsave("video.mp4", result, fps=4)
|
| 97 |
+
```
|
| 98 |
+
|
| 99 |
+
|
| 100 |
+
- #### SDXL Support
|
| 101 |
+
In order to use the SDXL model when generating a video from prompt, use the `TextToVideoZeroSDXLPipeline` pipeline:
|
| 102 |
+
|
| 103 |
+
```python
|
| 104 |
+
import torch
|
| 105 |
+
from diffusers import TextToVideoZeroSDXLPipeline
|
| 106 |
+
|
| 107 |
+
model_id = "stabilityai/stable-diffusion-xl-base-1.0"
|
| 108 |
+
pipe = TextToVideoZeroSDXLPipeline.from_pretrained(
|
| 109 |
+
model_id, torch_dtype=torch.float16, variant="fp16", use_safetensors=True
|
| 110 |
+
).to("cuda")
|
| 111 |
+
```
|
| 112 |
+
|
| 113 |
+
### Text-To-Video with Pose Control
|
| 114 |
+
To generate a video from prompt with additional pose control
|
| 115 |
+
|
| 116 |
+
1. Download a demo video
|
| 117 |
+
|
| 118 |
+
```python
|
| 119 |
+
from huggingface_hub import hf_hub_download
|
| 120 |
+
|
| 121 |
+
filename = "__assets__/poses_skeleton_gifs/dance1_corr.mp4"
|
| 122 |
+
repo_id = "PAIR/Text2Video-Zero"
|
| 123 |
+
video_path = hf_hub_download(repo_type="space", repo_id=repo_id, filename=filename)
|
| 124 |
+
```
|
| 125 |
+
|
| 126 |
+
|
| 127 |
+
2. Read video containing extracted pose images
|
| 128 |
+
```python
|
| 129 |
+
from PIL import Image
|
| 130 |
+
import imageio
|
| 131 |
+
|
| 132 |
+
reader = imageio.get_reader(video_path, "ffmpeg")
|
| 133 |
+
frame_count = 8
|
| 134 |
+
pose_images = [Image.fromarray(reader.get_data(i)) for i in range(frame_count)]
|
| 135 |
+
```
|
| 136 |
+
To extract pose from actual video, read [ControlNet documentation](controlnet).
|
| 137 |
+
|
| 138 |
+
3. Run `StableDiffusionControlNetPipeline` with our custom attention processor
|
| 139 |
+
|
| 140 |
+
```python
|
| 141 |
+
import torch
|
| 142 |
+
from diffusers import StableDiffusionControlNetPipeline, ControlNetModel
|
| 143 |
+
from diffusers.pipelines.text_to_video_synthesis.pipeline_text_to_video_zero import CrossFrameAttnProcessor
|
| 144 |
+
|
| 145 |
+
model_id = "stable-diffusion-v1-5/stable-diffusion-v1-5"
|
| 146 |
+
controlnet = ControlNetModel.from_pretrained("lllyasviel/sd-controlnet-openpose", torch_dtype=torch.float16)
|
| 147 |
+
pipe = StableDiffusionControlNetPipeline.from_pretrained(
|
| 148 |
+
model_id, controlnet=controlnet, torch_dtype=torch.float16
|
| 149 |
+
).to("cuda")
|
| 150 |
+
|
| 151 |
+
# Set the attention processor
|
| 152 |
+
pipe.unet.set_attn_processor(CrossFrameAttnProcessor(batch_size=2))
|
| 153 |
+
pipe.controlnet.set_attn_processor(CrossFrameAttnProcessor(batch_size=2))
|
| 154 |
+
|
| 155 |
+
# fix latents for all frames
|
| 156 |
+
latents = torch.randn((1, 4, 64, 64), device="cuda", dtype=torch.float16).repeat(len(pose_images), 1, 1, 1)
|
| 157 |
+
|
| 158 |
+
prompt = "Darth Vader dancing in a desert"
|
| 159 |
+
result = pipe(prompt=[prompt] * len(pose_images), image=pose_images, latents=latents).images
|
| 160 |
+
imageio.mimsave("video.mp4", result, fps=4)
|
| 161 |
+
```
|
| 162 |
+
- #### SDXL Support
|
| 163 |
+
|
| 164 |
+
Since our attention processor also works with SDXL, it can be utilized to generate a video from prompt using ControlNet models powered by SDXL:
|
| 165 |
+
```python
|
| 166 |
+
import torch
|
| 167 |
+
from diffusers import StableDiffusionXLControlNetPipeline, ControlNetModel
|
| 168 |
+
from diffusers.pipelines.text_to_video_synthesis.pipeline_text_to_video_zero import CrossFrameAttnProcessor
|
| 169 |
+
|
| 170 |
+
controlnet_model_id = 'thibaud/controlnet-openpose-sdxl-1.0'
|
| 171 |
+
model_id = 'stabilityai/stable-diffusion-xl-base-1.0'
|
| 172 |
+
|
| 173 |
+
controlnet = ControlNetModel.from_pretrained(controlnet_model_id, torch_dtype=torch.float16)
|
| 174 |
+
pipe = StableDiffusionControlNetPipeline.from_pretrained(
|
| 175 |
+
model_id, controlnet=controlnet, torch_dtype=torch.float16
|
| 176 |
+
).to('cuda')
|
| 177 |
+
|
| 178 |
+
# Set the attention processor
|
| 179 |
+
pipe.unet.set_attn_processor(CrossFrameAttnProcessor(batch_size=2))
|
| 180 |
+
pipe.controlnet.set_attn_processor(CrossFrameAttnProcessor(batch_size=2))
|
| 181 |
+
|
| 182 |
+
# fix latents for all frames
|
| 183 |
+
latents = torch.randn((1, 4, 128, 128), device="cuda", dtype=torch.float16).repeat(len(pose_images), 1, 1, 1)
|
| 184 |
+
|
| 185 |
+
prompt = "Darth Vader dancing in a desert"
|
| 186 |
+
result = pipe(prompt=[prompt] * len(pose_images), image=pose_images, latents=latents).images
|
| 187 |
+
imageio.mimsave("video.mp4", result, fps=4)
|
| 188 |
+
```
|
| 189 |
+
|
| 190 |
+
### Text-To-Video with Edge Control
|
| 191 |
+
|
| 192 |
+
To generate a video from prompt with additional Canny edge control, follow the same steps described above for pose-guided generation using [Canny edge ControlNet model](https://huggingface.co/lllyasviel/sd-controlnet-canny).
|
| 193 |
+
|
| 194 |
+
|
| 195 |
+
### Video Instruct-Pix2Pix
|
| 196 |
+
|
| 197 |
+
To perform text-guided video editing (with [InstructPix2Pix](pix2pix)):
|
| 198 |
+
|
| 199 |
+
1. Download a demo video
|
| 200 |
+
|
| 201 |
+
```python
|
| 202 |
+
from huggingface_hub import hf_hub_download
|
| 203 |
+
|
| 204 |
+
filename = "__assets__/pix2pix video/camel.mp4"
|
| 205 |
+
repo_id = "PAIR/Text2Video-Zero"
|
| 206 |
+
video_path = hf_hub_download(repo_type="space", repo_id=repo_id, filename=filename)
|
| 207 |
+
```
|
| 208 |
+
|
| 209 |
+
2. Read video from path
|
| 210 |
+
```python
|
| 211 |
+
from PIL import Image
|
| 212 |
+
import imageio
|
| 213 |
+
|
| 214 |
+
reader = imageio.get_reader(video_path, "ffmpeg")
|
| 215 |
+
frame_count = 8
|
| 216 |
+
video = [Image.fromarray(reader.get_data(i)) for i in range(frame_count)]
|
| 217 |
+
```
|
| 218 |
+
|
| 219 |
+
3. Run `StableDiffusionInstructPix2PixPipeline` with our custom attention processor
|
| 220 |
+
```python
|
| 221 |
+
import torch
|
| 222 |
+
from diffusers import StableDiffusionInstructPix2PixPipeline
|
| 223 |
+
from diffusers.pipelines.text_to_video_synthesis.pipeline_text_to_video_zero import CrossFrameAttnProcessor
|
| 224 |
+
|
| 225 |
+
model_id = "timbrooks/instruct-pix2pix"
|
| 226 |
+
pipe = StableDiffusionInstructPix2PixPipeline.from_pretrained(model_id, torch_dtype=torch.float16).to("cuda")
|
| 227 |
+
pipe.unet.set_attn_processor(CrossFrameAttnProcessor(batch_size=3))
|
| 228 |
+
|
| 229 |
+
prompt = "make it Van Gogh Starry Night style"
|
| 230 |
+
result = pipe(prompt=[prompt] * len(video), image=video).images
|
| 231 |
+
imageio.mimsave("edited_video.mp4", result, fps=4)
|
| 232 |
+
```
|
| 233 |
+
|
| 234 |
+
|
| 235 |
+
### DreamBooth specialization
|
| 236 |
+
|
| 237 |
+
Methods **Text-To-Video**, **Text-To-Video with Pose Control** and **Text-To-Video with Edge Control**
|
| 238 |
+
can run with custom [DreamBooth](../../training/dreambooth) models, as shown below for
|
| 239 |
+
[Canny edge ControlNet model](https://huggingface.co/lllyasviel/sd-controlnet-canny) and
|
| 240 |
+
[Avatar style DreamBooth](https://huggingface.co/PAIR/text2video-zero-controlnet-canny-avatar) model:
|
| 241 |
+
|
| 242 |
+
1. Download a demo video
|
| 243 |
+
|
| 244 |
+
```python
|
| 245 |
+
from huggingface_hub import hf_hub_download
|
| 246 |
+
|
| 247 |
+
filename = "__assets__/canny_videos_mp4/girl_turning.mp4"
|
| 248 |
+
repo_id = "PAIR/Text2Video-Zero"
|
| 249 |
+
video_path = hf_hub_download(repo_type="space", repo_id=repo_id, filename=filename)
|
| 250 |
+
```
|
| 251 |
+
|
| 252 |
+
2. Read video from path
|
| 253 |
+
```python
|
| 254 |
+
from PIL import Image
|
| 255 |
+
import imageio
|
| 256 |
+
|
| 257 |
+
reader = imageio.get_reader(video_path, "ffmpeg")
|
| 258 |
+
frame_count = 8
|
| 259 |
+
canny_edges = [Image.fromarray(reader.get_data(i)) for i in range(frame_count)]
|
| 260 |
+
```
|
| 261 |
+
|
| 262 |
+
3. Run `StableDiffusionControlNetPipeline` with custom trained DreamBooth model
|
| 263 |
+
```python
|
| 264 |
+
import torch
|
| 265 |
+
from diffusers import StableDiffusionControlNetPipeline, ControlNetModel
|
| 266 |
+
from diffusers.pipelines.text_to_video_synthesis.pipeline_text_to_video_zero import CrossFrameAttnProcessor
|
| 267 |
+
|
| 268 |
+
# set model id to custom model
|
| 269 |
+
model_id = "PAIR/text2video-zero-controlnet-canny-avatar"
|
| 270 |
+
controlnet = ControlNetModel.from_pretrained("lllyasviel/sd-controlnet-canny", torch_dtype=torch.float16)
|
| 271 |
+
pipe = StableDiffusionControlNetPipeline.from_pretrained(
|
| 272 |
+
model_id, controlnet=controlnet, torch_dtype=torch.float16
|
| 273 |
+
).to("cuda")
|
| 274 |
+
|
| 275 |
+
# Set the attention processor
|
| 276 |
+
pipe.unet.set_attn_processor(CrossFrameAttnProcessor(batch_size=2))
|
| 277 |
+
pipe.controlnet.set_attn_processor(CrossFrameAttnProcessor(batch_size=2))
|
| 278 |
+
|
| 279 |
+
# fix latents for all frames
|
| 280 |
+
latents = torch.randn((1, 4, 64, 64), device="cuda", dtype=torch.float16).repeat(len(canny_edges), 1, 1, 1)
|
| 281 |
+
|
| 282 |
+
prompt = "oil painting of a beautiful girl avatar style"
|
| 283 |
+
result = pipe(prompt=[prompt] * len(canny_edges), image=canny_edges, latents=latents).images
|
| 284 |
+
imageio.mimsave("video.mp4", result, fps=4)
|
| 285 |
+
```
|
| 286 |
+
|
| 287 |
+
You can filter out some available DreamBooth-trained models with [this link](https://huggingface.co/models?search=dreambooth).
|
| 288 |
+
|
| 289 |
+
<Tip>
|
| 290 |
+
|
| 291 |
+
Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines.
|
| 292 |
+
|
| 293 |
+
</Tip>
|
| 294 |
+
|
| 295 |
+
## TextToVideoZeroPipeline
|
| 296 |
+
[[autodoc]] TextToVideoZeroPipeline
|
| 297 |
+
- all
|
| 298 |
+
- __call__
|
| 299 |
+
|
| 300 |
+
## TextToVideoZeroSDXLPipeline
|
| 301 |
+
[[autodoc]] TextToVideoZeroSDXLPipeline
|
| 302 |
+
- all
|
| 303 |
+
- __call__
|
| 304 |
+
|
| 305 |
+
## TextToVideoPipelineOutput
|
| 306 |
+
[[autodoc]] pipelines.text_to_video_synthesis.pipeline_text_to_video_zero.TextToVideoPipelineOutput
|
tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/unclip.md
ADDED
|
@@ -0,0 +1,37 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 3 |
+
the License. You may obtain a copy of the License at
|
| 4 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 5 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 6 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 7 |
+
specific language governing permissions and limitations under the License.
|
| 8 |
+
-->
|
| 9 |
+
|
| 10 |
+
# unCLIP
|
| 11 |
+
|
| 12 |
+
[Hierarchical Text-Conditional Image Generation with CLIP Latents](https://huggingface.co/papers/2204.06125) is by Aditya Ramesh, Prafulla Dhariwal, Alex Nichol, Casey Chu, Mark Chen. The unCLIP model in 🤗 Diffusers comes from kakaobrain's [karlo](https://github.com/kakaobrain/karlo).
|
| 13 |
+
|
| 14 |
+
The abstract from the paper is following:
|
| 15 |
+
|
| 16 |
+
*Contrastive models like CLIP have been shown to learn robust representations of images that capture both semantics and style. To leverage these representations for image generation, we propose a two-stage model: a prior that generates a CLIP image embedding given a text caption, and a decoder that generates an image conditioned on the image embedding. We show that explicitly generating image representations improves image diversity with minimal loss in photorealism and caption similarity. Our decoders conditioned on image representations can also produce variations of an image that preserve both its semantics and style, while varying the non-essential details absent from the image representation. Moreover, the joint embedding space of CLIP enables language-guided image manipulations in a zero-shot fashion. We use diffusion models for the decoder and experiment with both autoregressive and diffusion models for the prior, finding that the latter are computationally more efficient and produce higher-quality samples.*
|
| 17 |
+
|
| 18 |
+
You can find lucidrains' DALL-E 2 recreation at [lucidrains/DALLE2-pytorch](https://github.com/lucidrains/DALLE2-pytorch).
|
| 19 |
+
|
| 20 |
+
<Tip>
|
| 21 |
+
|
| 22 |
+
Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines.
|
| 23 |
+
|
| 24 |
+
</Tip>
|
| 25 |
+
|
| 26 |
+
## UnCLIPPipeline
|
| 27 |
+
[[autodoc]] UnCLIPPipeline
|
| 28 |
+
- all
|
| 29 |
+
- __call__
|
| 30 |
+
|
| 31 |
+
## UnCLIPImageVariationPipeline
|
| 32 |
+
[[autodoc]] UnCLIPImageVariationPipeline
|
| 33 |
+
- all
|
| 34 |
+
- __call__
|
| 35 |
+
|
| 36 |
+
## ImagePipelineOutput
|
| 37 |
+
[[autodoc]] pipelines.ImagePipelineOutput
|
tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/unidiffuser.md
ADDED
|
@@ -0,0 +1,209 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# UniDiffuser
|
| 14 |
+
|
| 15 |
+
<div class="flex flex-wrap space-x-1">
|
| 16 |
+
<img alt="LoRA" src="https://img.shields.io/badge/LoRA-d8b4fe?style=flat"/>
|
| 17 |
+
</div>
|
| 18 |
+
|
| 19 |
+
The UniDiffuser model was proposed in [One Transformer Fits All Distributions in Multi-Modal Diffusion at Scale](https://huggingface.co/papers/2303.06555) by Fan Bao, Shen Nie, Kaiwen Xue, Chongxuan Li, Shi Pu, Yaole Wang, Gang Yue, Yue Cao, Hang Su, Jun Zhu.
|
| 20 |
+
|
| 21 |
+
The abstract from the paper is:
|
| 22 |
+
|
| 23 |
+
*This paper proposes a unified diffusion framework (dubbed UniDiffuser) to fit all distributions relevant to a set of multi-modal data in one model. Our key insight is -- learning diffusion models for marginal, conditional, and joint distributions can be unified as predicting the noise in the perturbed data, where the perturbation levels (i.e. timesteps) can be different for different modalities. Inspired by the unified view, UniDiffuser learns all distributions simultaneously with a minimal modification to the original diffusion model -- perturbs data in all modalities instead of a single modality, inputs individual timesteps in different modalities, and predicts the noise of all modalities instead of a single modality. UniDiffuser is parameterized by a transformer for diffusion models to handle input types of different modalities. Implemented on large-scale paired image-text data, UniDiffuser is able to perform image, text, text-to-image, image-to-text, and image-text pair generation by setting proper timesteps without additional overhead. In particular, UniDiffuser is able to produce perceptually realistic samples in all tasks and its quantitative results (e.g., the FID and CLIP score) are not only superior to existing general-purpose models but also comparable to the bespoken models (e.g., Stable Diffusion and DALL-E 2) in representative tasks (e.g., text-to-image generation).*
|
| 24 |
+
|
| 25 |
+
You can find the original codebase at [thu-ml/unidiffuser](https://github.com/thu-ml/unidiffuser) and additional checkpoints at [thu-ml](https://huggingface.co/thu-ml).
|
| 26 |
+
|
| 27 |
+
<Tip warning={true}>
|
| 28 |
+
|
| 29 |
+
There is currently an issue on PyTorch 1.X where the output images are all black or the pixel values become `NaNs`. This issue can be mitigated by switching to PyTorch 2.X.
|
| 30 |
+
|
| 31 |
+
</Tip>
|
| 32 |
+
|
| 33 |
+
This pipeline was contributed by [dg845](https://github.com/dg845). ❤️
|
| 34 |
+
|
| 35 |
+
## Usage Examples
|
| 36 |
+
|
| 37 |
+
Because the UniDiffuser model is trained to model the joint distribution of (image, text) pairs, it is capable of performing a diverse range of generation tasks:
|
| 38 |
+
|
| 39 |
+
### Unconditional Image and Text Generation
|
| 40 |
+
|
| 41 |
+
Unconditional generation (where we start from only latents sampled from a standard Gaussian prior) from a [`UniDiffuserPipeline`] will produce a (image, text) pair:
|
| 42 |
+
|
| 43 |
+
```python
|
| 44 |
+
import torch
|
| 45 |
+
|
| 46 |
+
from diffusers import UniDiffuserPipeline
|
| 47 |
+
|
| 48 |
+
device = "cuda"
|
| 49 |
+
model_id_or_path = "thu-ml/unidiffuser-v1"
|
| 50 |
+
pipe = UniDiffuserPipeline.from_pretrained(model_id_or_path, torch_dtype=torch.float16)
|
| 51 |
+
pipe.to(device)
|
| 52 |
+
|
| 53 |
+
# Unconditional image and text generation. The generation task is automatically inferred.
|
| 54 |
+
sample = pipe(num_inference_steps=20, guidance_scale=8.0)
|
| 55 |
+
image = sample.images[0]
|
| 56 |
+
text = sample.text[0]
|
| 57 |
+
image.save("unidiffuser_joint_sample_image.png")
|
| 58 |
+
print(text)
|
| 59 |
+
```
|
| 60 |
+
|
| 61 |
+
This is also called "joint" generation in the UniDiffuser paper, since we are sampling from the joint image-text distribution.
|
| 62 |
+
|
| 63 |
+
Note that the generation task is inferred from the inputs used when calling the pipeline.
|
| 64 |
+
It is also possible to manually specify the unconditional generation task ("mode") manually with [`UniDiffuserPipeline.set_joint_mode`]:
|
| 65 |
+
|
| 66 |
+
```python
|
| 67 |
+
# Equivalent to the above.
|
| 68 |
+
pipe.set_joint_mode()
|
| 69 |
+
sample = pipe(num_inference_steps=20, guidance_scale=8.0)
|
| 70 |
+
```
|
| 71 |
+
|
| 72 |
+
When the mode is set manually, subsequent calls to the pipeline will use the set mode without attempting to infer the mode.
|
| 73 |
+
You can reset the mode with [`UniDiffuserPipeline.reset_mode`], after which the pipeline will once again infer the mode.
|
| 74 |
+
|
| 75 |
+
You can also generate only an image or only text (which the UniDiffuser paper calls "marginal" generation since we sample from the marginal distribution of images and text, respectively):
|
| 76 |
+
|
| 77 |
+
```python
|
| 78 |
+
# Unlike other generation tasks, image-only and text-only generation don't use classifier-free guidance
|
| 79 |
+
# Image-only generation
|
| 80 |
+
pipe.set_image_mode()
|
| 81 |
+
sample_image = pipe(num_inference_steps=20).images[0]
|
| 82 |
+
# Text-only generation
|
| 83 |
+
pipe.set_text_mode()
|
| 84 |
+
sample_text = pipe(num_inference_steps=20).text[0]
|
| 85 |
+
```
|
| 86 |
+
|
| 87 |
+
### Text-to-Image Generation
|
| 88 |
+
|
| 89 |
+
UniDiffuser is also capable of sampling from conditional distributions; that is, the distribution of images conditioned on a text prompt or the distribution of texts conditioned on an image.
|
| 90 |
+
Here is an example of sampling from the conditional image distribution (text-to-image generation or text-conditioned image generation):
|
| 91 |
+
|
| 92 |
+
```python
|
| 93 |
+
import torch
|
| 94 |
+
|
| 95 |
+
from diffusers import UniDiffuserPipeline
|
| 96 |
+
|
| 97 |
+
device = "cuda"
|
| 98 |
+
model_id_or_path = "thu-ml/unidiffuser-v1"
|
| 99 |
+
pipe = UniDiffuserPipeline.from_pretrained(model_id_or_path, torch_dtype=torch.float16)
|
| 100 |
+
pipe.to(device)
|
| 101 |
+
|
| 102 |
+
# Text-to-image generation
|
| 103 |
+
prompt = "an elephant under the sea"
|
| 104 |
+
|
| 105 |
+
sample = pipe(prompt=prompt, num_inference_steps=20, guidance_scale=8.0)
|
| 106 |
+
t2i_image = sample.images[0]
|
| 107 |
+
t2i_image
|
| 108 |
+
```
|
| 109 |
+
|
| 110 |
+
The `text2img` mode requires that either an input `prompt` or `prompt_embeds` be supplied. You can set the `text2img` mode manually with [`UniDiffuserPipeline.set_text_to_image_mode`].
|
| 111 |
+
|
| 112 |
+
### Image-to-Text Generation
|
| 113 |
+
|
| 114 |
+
Similarly, UniDiffuser can also produce text samples given an image (image-to-text or image-conditioned text generation):
|
| 115 |
+
|
| 116 |
+
```python
|
| 117 |
+
import torch
|
| 118 |
+
|
| 119 |
+
from diffusers import UniDiffuserPipeline
|
| 120 |
+
from diffusers.utils import load_image
|
| 121 |
+
|
| 122 |
+
device = "cuda"
|
| 123 |
+
model_id_or_path = "thu-ml/unidiffuser-v1"
|
| 124 |
+
pipe = UniDiffuserPipeline.from_pretrained(model_id_or_path, torch_dtype=torch.float16)
|
| 125 |
+
pipe.to(device)
|
| 126 |
+
|
| 127 |
+
# Image-to-text generation
|
| 128 |
+
image_url = "https://huggingface.co/datasets/hf-internal-testing/diffusers-images/resolve/main/unidiffuser/unidiffuser_example_image.jpg"
|
| 129 |
+
init_image = load_image(image_url).resize((512, 512))
|
| 130 |
+
|
| 131 |
+
sample = pipe(image=init_image, num_inference_steps=20, guidance_scale=8.0)
|
| 132 |
+
i2t_text = sample.text[0]
|
| 133 |
+
print(i2t_text)
|
| 134 |
+
```
|
| 135 |
+
|
| 136 |
+
The `img2text` mode requires that an input `image` be supplied. You can set the `img2text` mode manually with [`UniDiffuserPipeline.set_image_to_text_mode`].
|
| 137 |
+
|
| 138 |
+
### Image Variation
|
| 139 |
+
|
| 140 |
+
The UniDiffuser authors suggest performing image variation through a "round-trip" generation method, where given an input image, we first perform an image-to-text generation, and then perform a text-to-image generation on the outputs of the first generation.
|
| 141 |
+
This produces a new image which is semantically similar to the input image:
|
| 142 |
+
|
| 143 |
+
```python
|
| 144 |
+
import torch
|
| 145 |
+
|
| 146 |
+
from diffusers import UniDiffuserPipeline
|
| 147 |
+
from diffusers.utils import load_image
|
| 148 |
+
|
| 149 |
+
device = "cuda"
|
| 150 |
+
model_id_or_path = "thu-ml/unidiffuser-v1"
|
| 151 |
+
pipe = UniDiffuserPipeline.from_pretrained(model_id_or_path, torch_dtype=torch.float16)
|
| 152 |
+
pipe.to(device)
|
| 153 |
+
|
| 154 |
+
# Image variation can be performed with an image-to-text generation followed by a text-to-image generation:
|
| 155 |
+
# 1. Image-to-text generation
|
| 156 |
+
image_url = "https://huggingface.co/datasets/hf-internal-testing/diffusers-images/resolve/main/unidiffuser/unidiffuser_example_image.jpg"
|
| 157 |
+
init_image = load_image(image_url).resize((512, 512))
|
| 158 |
+
|
| 159 |
+
sample = pipe(image=init_image, num_inference_steps=20, guidance_scale=8.0)
|
| 160 |
+
i2t_text = sample.text[0]
|
| 161 |
+
print(i2t_text)
|
| 162 |
+
|
| 163 |
+
# 2. Text-to-image generation
|
| 164 |
+
sample = pipe(prompt=i2t_text, num_inference_steps=20, guidance_scale=8.0)
|
| 165 |
+
final_image = sample.images[0]
|
| 166 |
+
final_image.save("unidiffuser_image_variation_sample.png")
|
| 167 |
+
```
|
| 168 |
+
|
| 169 |
+
### Text Variation
|
| 170 |
+
|
| 171 |
+
Similarly, text variation can be performed on an input prompt with a text-to-image generation followed by a image-to-text generation:
|
| 172 |
+
|
| 173 |
+
```python
|
| 174 |
+
import torch
|
| 175 |
+
|
| 176 |
+
from diffusers import UniDiffuserPipeline
|
| 177 |
+
|
| 178 |
+
device = "cuda"
|
| 179 |
+
model_id_or_path = "thu-ml/unidiffuser-v1"
|
| 180 |
+
pipe = UniDiffuserPipeline.from_pretrained(model_id_or_path, torch_dtype=torch.float16)
|
| 181 |
+
pipe.to(device)
|
| 182 |
+
|
| 183 |
+
# Text variation can be performed with a text-to-image generation followed by a image-to-text generation:
|
| 184 |
+
# 1. Text-to-image generation
|
| 185 |
+
prompt = "an elephant under the sea"
|
| 186 |
+
|
| 187 |
+
sample = pipe(prompt=prompt, num_inference_steps=20, guidance_scale=8.0)
|
| 188 |
+
t2i_image = sample.images[0]
|
| 189 |
+
t2i_image.save("unidiffuser_text2img_sample_image.png")
|
| 190 |
+
|
| 191 |
+
# 2. Image-to-text generation
|
| 192 |
+
sample = pipe(image=t2i_image, num_inference_steps=20, guidance_scale=8.0)
|
| 193 |
+
final_prompt = sample.text[0]
|
| 194 |
+
print(final_prompt)
|
| 195 |
+
```
|
| 196 |
+
|
| 197 |
+
<Tip>
|
| 198 |
+
|
| 199 |
+
Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines.
|
| 200 |
+
|
| 201 |
+
</Tip>
|
| 202 |
+
|
| 203 |
+
## UniDiffuserPipeline
|
| 204 |
+
[[autodoc]] UniDiffuserPipeline
|
| 205 |
+
- all
|
| 206 |
+
- __call__
|
| 207 |
+
|
| 208 |
+
## ImageTextPipelineOutput
|
| 209 |
+
[[autodoc]] pipelines.ImageTextPipelineOutput
|
tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/value_guided_sampling.md
ADDED
|
@@ -0,0 +1,38 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Value-guided planning
|
| 14 |
+
|
| 15 |
+
<Tip warning={true}>
|
| 16 |
+
|
| 17 |
+
🧪 This is an experimental pipeline for reinforcement learning!
|
| 18 |
+
|
| 19 |
+
</Tip>
|
| 20 |
+
|
| 21 |
+
This pipeline is based on the [Planning with Diffusion for Flexible Behavior Synthesis](https://huggingface.co/papers/2205.09991) paper by Michael Janner, Yilun Du, Joshua B. Tenenbaum, Sergey Levine.
|
| 22 |
+
|
| 23 |
+
The abstract from the paper is:
|
| 24 |
+
|
| 25 |
+
*Model-based reinforcement learning methods often use learning only for the purpose of estimating an approximate dynamics model, offloading the rest of the decision-making work to classical trajectory optimizers. While conceptually simple, this combination has a number of empirical shortcomings, suggesting that learned models may not be well-suited to standard trajectory optimization. In this paper, we consider what it would look like to fold as much of the trajectory optimization pipeline as possible into the modeling problem, such that sampling from the model and planning with it become nearly identical. The core of our technical approach lies in a diffusion probabilistic model that plans by iteratively denoising trajectories. We show how classifier-guided sampling and image inpainting can be reinterpreted as coherent planning strategies, explore the unusual and useful properties of diffusion-based planning methods, and demonstrate the effectiveness of our framework in control settings that emphasize long-horizon decision-making and test-time flexibility.*
|
| 26 |
+
|
| 27 |
+
You can find additional information about the model on the [project page](https://diffusion-planning.github.io/), the [original codebase](https://github.com/jannerm/diffuser), or try it out in a demo [notebook](https://colab.research.google.com/drive/1rXm8CX4ZdN5qivjJ2lhwhkOmt_m0CvU0#scrollTo=6HXJvhyqcITc&uniqifier=1).
|
| 28 |
+
|
| 29 |
+
The script to run the model is available [here](https://github.com/huggingface/diffusers/tree/main/examples/reinforcement_learning).
|
| 30 |
+
|
| 31 |
+
<Tip>
|
| 32 |
+
|
| 33 |
+
Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines.
|
| 34 |
+
|
| 35 |
+
</Tip>
|
| 36 |
+
|
| 37 |
+
## ValueGuidedRLPipeline
|
| 38 |
+
[[autodoc]] diffusers.experimental.ValueGuidedRLPipeline
|
tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/visualcloze.md
ADDED
|
@@ -0,0 +1,300 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
#
|
| 3 |
+
# Licensed under the Apache License, Version 2.0 (the "License");
|
| 4 |
+
# you may not use this file except in compliance with the License.
|
| 5 |
+
# You may obtain a copy of the License at
|
| 6 |
+
#
|
| 7 |
+
# http://www.apache.org/licenses/LICENSE-2.0
|
| 8 |
+
#
|
| 9 |
+
# Unless required by applicable law or agreed to in writing, software
|
| 10 |
+
# distributed under the License is distributed on an "AS IS" BASIS,
|
| 11 |
+
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
| 12 |
+
# See the License for the specific language governing permissions and
|
| 13 |
+
# limitations under the License.
|
| 14 |
+
-->
|
| 15 |
+
|
| 16 |
+
# VisualCloze
|
| 17 |
+
|
| 18 |
+
[VisualCloze: A Universal Image Generation Framework via Visual In-Context Learning](https://huggingface.co/papers/2504.07960) is an innovative in-context learning based universal image generation framework that offers key capabilities:
|
| 19 |
+
1. Support for various in-domain tasks
|
| 20 |
+
2. Generalization to unseen tasks through in-context learning
|
| 21 |
+
3. Unify multiple tasks into one step and generate both target image and intermediate results
|
| 22 |
+
4. Support reverse-engineering conditions from target images
|
| 23 |
+
|
| 24 |
+
## Overview
|
| 25 |
+
|
| 26 |
+
The abstract from the paper is:
|
| 27 |
+
|
| 28 |
+
*Recent progress in diffusion models significantly advances various image generation tasks. However, the current mainstream approach remains focused on building task-specific models, which have limited efficiency when supporting a wide range of different needs. While universal models attempt to address this limitation, they face critical challenges, including generalizable task instruction, appropriate task distributions, and unified architectural design. To tackle these challenges, we propose VisualCloze, a universal image generation framework, which supports a wide range of in-domain tasks, generalization to unseen ones, unseen unification of multiple tasks, and reverse generation. Unlike existing methods that rely on language-based task instruction, leading to task ambiguity and weak generalization, we integrate visual in-context learning, allowing models to identify tasks from visual demonstrations. Meanwhile, the inherent sparsity of visual task distributions hampers the learning of transferable knowledge across tasks. To this end, we introduce Graph200K, a graph-structured dataset that establishes various interrelated tasks, enhancing task density and transferable knowledge. Furthermore, we uncover that our unified image generation formulation shared a consistent objective with image infilling, enabling us to leverage the strong generative priors of pre-trained infilling models without modifying the architectures. The codes, dataset, and models are available at https://visualcloze.github.io.*
|
| 29 |
+
|
| 30 |
+
## Inference
|
| 31 |
+
|
| 32 |
+
### Model loading
|
| 33 |
+
|
| 34 |
+
VisualCloze is a two-stage cascade pipeline, containing `VisualClozeGenerationPipeline` and `VisualClozeUpsamplingPipeline`.
|
| 35 |
+
- In `VisualClozeGenerationPipeline`, each image is downsampled before concatenating images into a grid layout, avoiding excessively high resolutions. VisualCloze releases two models suitable for diffusers, i.e., [VisualClozePipeline-384](https://huggingface.co/VisualCloze/VisualClozePipeline-384) and [VisualClozePipeline-512](https://huggingface.co/VisualCloze/VisualClozePipeline-384), which downsample images to resolutions of 384 and 512, respectively.
|
| 36 |
+
- `VisualClozeUpsamplingPipeline` uses [SDEdit](https://huggingface.co/papers/2108.01073) to enable high-resolution image synthesis.
|
| 37 |
+
|
| 38 |
+
The `VisualClozePipeline` integrates both stages to support convenient end-to-end sampling, while also allowing users to utilize each pipeline independently as needed.
|
| 39 |
+
|
| 40 |
+
### Input Specifications
|
| 41 |
+
|
| 42 |
+
#### Task and Content Prompts
|
| 43 |
+
- Task prompt: Required to describe the generation task intention
|
| 44 |
+
- Content prompt: Optional description or caption of the target image
|
| 45 |
+
- When content prompt is not needed, pass `None`
|
| 46 |
+
- For batch inference, pass `List[str|None]`
|
| 47 |
+
|
| 48 |
+
#### Image Input Format
|
| 49 |
+
- Format: `List[List[Image|None]]`
|
| 50 |
+
- Structure:
|
| 51 |
+
- All rows except the last represent in-context examples
|
| 52 |
+
- Last row represents the current query (target image set to `None`)
|
| 53 |
+
- For batch inference, pass `List[List[List[Image|None]]]`
|
| 54 |
+
|
| 55 |
+
#### Resolution Control
|
| 56 |
+
- Default behavior:
|
| 57 |
+
- Initial generation in the first stage: area of ${pipe.resolution}^2$
|
| 58 |
+
- Upsampling in the second stage: 3x factor
|
| 59 |
+
- Custom resolution: Adjust using `upsampling_height` and `upsampling_width` parameters
|
| 60 |
+
|
| 61 |
+
### Examples
|
| 62 |
+
|
| 63 |
+
For comprehensive examples covering a wide range of tasks, please refer to the [Online Demo](https://huggingface.co/spaces/VisualCloze/VisualCloze) and [GitHub Repository](https://github.com/lzyhha/VisualCloze). Below are simple examples for three cases: mask-to-image conversion, edge detection, and subject-driven generation.
|
| 64 |
+
|
| 65 |
+
#### Example for mask2image
|
| 66 |
+
|
| 67 |
+
```python
|
| 68 |
+
import torch
|
| 69 |
+
from diffusers import VisualClozePipeline
|
| 70 |
+
from diffusers.utils import load_image
|
| 71 |
+
|
| 72 |
+
pipe = VisualClozePipeline.from_pretrained("VisualCloze/VisualClozePipeline-384", resolution=384, torch_dtype=torch.bfloat16)
|
| 73 |
+
pipe.to("cuda")
|
| 74 |
+
|
| 75 |
+
# Load in-context images (make sure the paths are correct and accessible)
|
| 76 |
+
image_paths = [
|
| 77 |
+
# in-context examples
|
| 78 |
+
[
|
| 79 |
+
load_image('https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/visualcloze/visualcloze_mask2image_incontext-example-1_mask.jpg'),
|
| 80 |
+
load_image('https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/visualcloze/visualcloze_mask2image_incontext-example-1_image.jpg'),
|
| 81 |
+
],
|
| 82 |
+
# query with the target image
|
| 83 |
+
[
|
| 84 |
+
load_image('https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/visualcloze/visualcloze_mask2image_query_mask.jpg'),
|
| 85 |
+
None, # No image needed for the target image
|
| 86 |
+
],
|
| 87 |
+
]
|
| 88 |
+
|
| 89 |
+
# Task and content prompt
|
| 90 |
+
task_prompt = "In each row, a logical task is demonstrated to achieve [IMAGE2] an aesthetically pleasing photograph based on [IMAGE1] sam 2-generated masks with rich color coding."
|
| 91 |
+
content_prompt = """Majestic photo of a golden eagle perched on a rocky outcrop in a mountainous landscape.
|
| 92 |
+
The eagle is positioned in the right foreground, facing left, with its sharp beak and keen eyes prominently visible.
|
| 93 |
+
Its plumage is a mix of dark brown and golden hues, with intricate feather details.
|
| 94 |
+
The background features a soft-focus view of snow-capped mountains under a cloudy sky, creating a serene and grandiose atmosphere.
|
| 95 |
+
The foreground includes rugged rocks and patches of green moss. Photorealistic, medium depth of field,
|
| 96 |
+
soft natural lighting, cool color palette, high contrast, sharp focus on the eagle, blurred background,
|
| 97 |
+
tranquil, majestic, wildlife photography."""
|
| 98 |
+
|
| 99 |
+
# Run the pipeline
|
| 100 |
+
image_result = pipe(
|
| 101 |
+
task_prompt=task_prompt,
|
| 102 |
+
content_prompt=content_prompt,
|
| 103 |
+
image=image_paths,
|
| 104 |
+
upsampling_width=1344,
|
| 105 |
+
upsampling_height=768,
|
| 106 |
+
upsampling_strength=0.4,
|
| 107 |
+
guidance_scale=30,
|
| 108 |
+
num_inference_steps=30,
|
| 109 |
+
max_sequence_length=512,
|
| 110 |
+
generator=torch.Generator("cpu").manual_seed(0)
|
| 111 |
+
).images[0][0]
|
| 112 |
+
|
| 113 |
+
# Save the resulting image
|
| 114 |
+
image_result.save("visualcloze.png")
|
| 115 |
+
```
|
| 116 |
+
|
| 117 |
+
#### Example for edge-detection
|
| 118 |
+
|
| 119 |
+
```python
|
| 120 |
+
import torch
|
| 121 |
+
from diffusers import VisualClozePipeline
|
| 122 |
+
from diffusers.utils import load_image
|
| 123 |
+
|
| 124 |
+
pipe = VisualClozePipeline.from_pretrained("VisualCloze/VisualClozePipeline-384", resolution=384, torch_dtype=torch.bfloat16)
|
| 125 |
+
pipe.to("cuda")
|
| 126 |
+
|
| 127 |
+
# Load in-context images (make sure the paths are correct and accessible)
|
| 128 |
+
image_paths = [
|
| 129 |
+
# in-context examples
|
| 130 |
+
[
|
| 131 |
+
load_image('https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/visualcloze/visualcloze_edgedetection_incontext-example-1_image.jpg'),
|
| 132 |
+
load_image('https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/visualcloze/visualcloze_edgedetection_incontext-example-1_edge.jpg'),
|
| 133 |
+
],
|
| 134 |
+
[
|
| 135 |
+
load_image('https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/visualcloze/visualcloze_edgedetection_incontext-example-2_image.jpg'),
|
| 136 |
+
load_image('https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/visualcloze/visualcloze_edgedetection_incontext-example-2_edge.jpg'),
|
| 137 |
+
],
|
| 138 |
+
# query with the target image
|
| 139 |
+
[
|
| 140 |
+
load_image('https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/visualcloze/visualcloze_edgedetection_query_image.jpg'),
|
| 141 |
+
None, # No image needed for the target image
|
| 142 |
+
],
|
| 143 |
+
]
|
| 144 |
+
|
| 145 |
+
# Task and content prompt
|
| 146 |
+
task_prompt = "Each row illustrates a pathway from [IMAGE1] a sharp and beautifully composed photograph to [IMAGE2] edge map with natural well-connected outlines using a clear logical task."
|
| 147 |
+
content_prompt = ""
|
| 148 |
+
|
| 149 |
+
# Run the pipeline
|
| 150 |
+
image_result = pipe(
|
| 151 |
+
task_prompt=task_prompt,
|
| 152 |
+
content_prompt=content_prompt,
|
| 153 |
+
image=image_paths,
|
| 154 |
+
upsampling_width=864,
|
| 155 |
+
upsampling_height=1152,
|
| 156 |
+
upsampling_strength=0.4,
|
| 157 |
+
guidance_scale=30,
|
| 158 |
+
num_inference_steps=30,
|
| 159 |
+
max_sequence_length=512,
|
| 160 |
+
generator=torch.Generator("cpu").manual_seed(0)
|
| 161 |
+
).images[0][0]
|
| 162 |
+
|
| 163 |
+
# Save the resulting image
|
| 164 |
+
image_result.save("visualcloze.png")
|
| 165 |
+
```
|
| 166 |
+
|
| 167 |
+
#### Example for subject-driven generation
|
| 168 |
+
|
| 169 |
+
```python
|
| 170 |
+
import torch
|
| 171 |
+
from diffusers import VisualClozePipeline
|
| 172 |
+
from diffusers.utils import load_image
|
| 173 |
+
|
| 174 |
+
pipe = VisualClozePipeline.from_pretrained("VisualCloze/VisualClozePipeline-384", resolution=384, torch_dtype=torch.bfloat16)
|
| 175 |
+
pipe.to("cuda")
|
| 176 |
+
|
| 177 |
+
# Load in-context images (make sure the paths are correct and accessible)
|
| 178 |
+
image_paths = [
|
| 179 |
+
# in-context examples
|
| 180 |
+
[
|
| 181 |
+
load_image('https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/visualcloze/visualcloze_subjectdriven_incontext-example-1_reference.jpg'),
|
| 182 |
+
load_image('https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/visualcloze/visualcloze_subjectdriven_incontext-example-1_depth.jpg'),
|
| 183 |
+
load_image('https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/visualcloze/visualcloze_subjectdriven_incontext-example-1_image.jpg'),
|
| 184 |
+
],
|
| 185 |
+
[
|
| 186 |
+
load_image('https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/visualcloze/visualcloze_subjectdriven_incontext-example-2_reference.jpg'),
|
| 187 |
+
load_image('https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/visualcloze/visualcloze_subjectdriven_incontext-example-2_depth.jpg'),
|
| 188 |
+
load_image('https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/visualcloze/visualcloze_subjectdriven_incontext-example-2_image.jpg'),
|
| 189 |
+
],
|
| 190 |
+
# query with the target image
|
| 191 |
+
[
|
| 192 |
+
load_image('https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/visualcloze/visualcloze_subjectdriven_query_reference.jpg'),
|
| 193 |
+
load_image('https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/visualcloze/visualcloze_subjectdriven_query_depth.jpg'),
|
| 194 |
+
None, # No image needed for the target image
|
| 195 |
+
],
|
| 196 |
+
]
|
| 197 |
+
|
| 198 |
+
# Task and content prompt
|
| 199 |
+
task_prompt = """Each row describes a process that begins with [IMAGE1] an image containing the key object,
|
| 200 |
+
[IMAGE2] depth map revealing gray-toned spatial layers and results in
|
| 201 |
+
[IMAGE3] an image with artistic qualitya high-quality image with exceptional detail."""
|
| 202 |
+
content_prompt = """A vintage porcelain collector's item. Beneath a blossoming cherry tree in early spring,
|
| 203 |
+
this treasure is photographed up close, with soft pink petals drifting through the air and vibrant blossoms framing the scene."""
|
| 204 |
+
|
| 205 |
+
# Run the pipeline
|
| 206 |
+
image_result = pipe(
|
| 207 |
+
task_prompt=task_prompt,
|
| 208 |
+
content_prompt=content_prompt,
|
| 209 |
+
image=image_paths,
|
| 210 |
+
upsampling_width=1024,
|
| 211 |
+
upsampling_height=1024,
|
| 212 |
+
upsampling_strength=0.2,
|
| 213 |
+
guidance_scale=30,
|
| 214 |
+
num_inference_steps=30,
|
| 215 |
+
max_sequence_length=512,
|
| 216 |
+
generator=torch.Generator("cpu").manual_seed(0)
|
| 217 |
+
).images[0][0]
|
| 218 |
+
|
| 219 |
+
# Save the resulting image
|
| 220 |
+
image_result.save("visualcloze.png")
|
| 221 |
+
```
|
| 222 |
+
|
| 223 |
+
#### Utilize each pipeline independently
|
| 224 |
+
|
| 225 |
+
```python
|
| 226 |
+
import torch
|
| 227 |
+
from diffusers import VisualClozeGenerationPipeline, FluxFillPipeline as VisualClozeUpsamplingPipeline
|
| 228 |
+
from diffusers.utils import load_image
|
| 229 |
+
from PIL import Image
|
| 230 |
+
|
| 231 |
+
pipe = VisualClozeGenerationPipeline.from_pretrained(
|
| 232 |
+
"VisualCloze/VisualClozePipeline-384", resolution=384, torch_dtype=torch.bfloat16
|
| 233 |
+
)
|
| 234 |
+
pipe.to("cuda")
|
| 235 |
+
|
| 236 |
+
image_paths = [
|
| 237 |
+
# in-context examples
|
| 238 |
+
[
|
| 239 |
+
load_image(
|
| 240 |
+
"https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/visualcloze/visualcloze_mask2image_incontext-example-1_mask.jpg"
|
| 241 |
+
),
|
| 242 |
+
load_image(
|
| 243 |
+
"https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/visualcloze/visualcloze_mask2image_incontext-example-1_image.jpg"
|
| 244 |
+
),
|
| 245 |
+
],
|
| 246 |
+
# query with the target image
|
| 247 |
+
[
|
| 248 |
+
load_image(
|
| 249 |
+
"https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/visualcloze/visualcloze_mask2image_query_mask.jpg"
|
| 250 |
+
),
|
| 251 |
+
None, # No image needed for the target image
|
| 252 |
+
],
|
| 253 |
+
]
|
| 254 |
+
task_prompt = "In each row, a logical task is demonstrated to achieve [IMAGE2] an aesthetically pleasing photograph based on [IMAGE1] sam 2-generated masks with rich color coding."
|
| 255 |
+
content_prompt = "Majestic photo of a golden eagle perched on a rocky outcrop in a mountainous landscape. The eagle is positioned in the right foreground, facing left, with its sharp beak and keen eyes prominently visible. Its plumage is a mix of dark brown and golden hues, with intricate feather details. The background features a soft-focus view of snow-capped mountains under a cloudy sky, creating a serene and grandiose atmosphere. The foreground includes rugged rocks and patches of green moss. Photorealistic, medium depth of field, soft natural lighting, cool color palette, high contrast, sharp focus on the eagle, blurred background, tranquil, majestic, wildlife photography."
|
| 256 |
+
|
| 257 |
+
# Stage 1: Generate initial image
|
| 258 |
+
image = pipe(
|
| 259 |
+
task_prompt=task_prompt,
|
| 260 |
+
content_prompt=content_prompt,
|
| 261 |
+
image=image_paths,
|
| 262 |
+
guidance_scale=30,
|
| 263 |
+
num_inference_steps=30,
|
| 264 |
+
max_sequence_length=512,
|
| 265 |
+
generator=torch.Generator("cpu").manual_seed(0),
|
| 266 |
+
).images[0][0]
|
| 267 |
+
|
| 268 |
+
# Stage 2 (optional): Upsample the generated image
|
| 269 |
+
pipe_upsample = VisualClozeUpsamplingPipeline.from_pipe(pipe)
|
| 270 |
+
pipe_upsample.to("cuda")
|
| 271 |
+
|
| 272 |
+
mask_image = Image.new("RGB", image.size, (255, 255, 255))
|
| 273 |
+
|
| 274 |
+
image = pipe_upsample(
|
| 275 |
+
image=image,
|
| 276 |
+
mask_image=mask_image,
|
| 277 |
+
prompt=content_prompt,
|
| 278 |
+
width=1344,
|
| 279 |
+
height=768,
|
| 280 |
+
strength=0.4,
|
| 281 |
+
guidance_scale=30,
|
| 282 |
+
num_inference_steps=30,
|
| 283 |
+
max_sequence_length=512,
|
| 284 |
+
generator=torch.Generator("cpu").manual_seed(0),
|
| 285 |
+
).images[0]
|
| 286 |
+
|
| 287 |
+
image.save("visualcloze.png")
|
| 288 |
+
```
|
| 289 |
+
|
| 290 |
+
## VisualClozePipeline
|
| 291 |
+
|
| 292 |
+
[[autodoc]] VisualClozePipeline
|
| 293 |
+
- all
|
| 294 |
+
- __call__
|
| 295 |
+
|
| 296 |
+
## VisualClozeGenerationPipeline
|
| 297 |
+
|
| 298 |
+
[[autodoc]] VisualClozeGenerationPipeline
|
| 299 |
+
- all
|
| 300 |
+
- __call__
|
tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/wan.md
ADDED
|
@@ -0,0 +1,356 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!-- Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
#
|
| 3 |
+
# Licensed under the Apache License, Version 2.0 (the "License");
|
| 4 |
+
# you may not use this file except in compliance with the License.
|
| 5 |
+
# You may obtain a copy of the License at
|
| 6 |
+
#
|
| 7 |
+
# http://www.apache.org/licenses/LICENSE-2.0
|
| 8 |
+
#
|
| 9 |
+
# Unless required by applicable law or agreed to in writing, software
|
| 10 |
+
# distributed under the License is distributed on an "AS IS" BASIS,
|
| 11 |
+
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
| 12 |
+
# See the License for the specific language governing permissions and
|
| 13 |
+
# limitations under the License. -->
|
| 14 |
+
|
| 15 |
+
<div style="float: right;">
|
| 16 |
+
<div class="flex flex-wrap space-x-1">
|
| 17 |
+
<a href="https://huggingface.co/docs/diffusers/main/en/tutorials/using_peft_for_inference" target="_blank" rel="noopener">
|
| 18 |
+
<img alt="LoRA" src="https://img.shields.io/badge/LoRA-d8b4fe?style=flat"/>
|
| 19 |
+
</a>
|
| 20 |
+
</div>
|
| 21 |
+
</div>
|
| 22 |
+
|
| 23 |
+
# Wan2.1
|
| 24 |
+
|
| 25 |
+
[Wan-2.1](https://huggingface.co/papers/2503.20314) by the Wan Team.
|
| 26 |
+
|
| 27 |
+
*This report presents Wan, a comprehensive and open suite of video foundation models designed to push the boundaries of video generation. Built upon the mainstream diffusion transformer paradigm, Wan achieves significant advancements in generative capabilities through a series of innovations, including our novel VAE, scalable pre-training strategies, large-scale data curation, and automated evaluation metrics. These contributions collectively enhance the model's performance and versatility. Specifically, Wan is characterized by four key features: Leading Performance: The 14B model of Wan, trained on a vast dataset comprising billions of images and videos, demonstrates the scaling laws of video generation with respect to both data and model size. It consistently outperforms the existing open-source models as well as state-of-the-art commercial solutions across multiple internal and external benchmarks, demonstrating a clear and significant performance superiority. Comprehensiveness: Wan offers two capable models, i.e., 1.3B and 14B parameters, for efficiency and effectiveness respectively. It also covers multiple downstream applications, including image-to-video, instruction-guided video editing, and personal video generation, encompassing up to eight tasks. Consumer-Grade Efficiency: The 1.3B model demonstrates exceptional resource efficiency, requiring only 8.19 GB VRAM, making it compatible with a wide range of consumer-grade GPUs. Openness: We open-source the entire series of Wan, including source code and all models, with the goal of fostering the growth of the video generation community. This openness seeks to significantly expand the creative possibilities of video production in the industry and provide academia with high-quality video foundation models. All the code and models are available at [this https URL](https://github.com/Wan-Video/Wan2.1).*
|
| 28 |
+
|
| 29 |
+
You can find all the original Wan2.1 checkpoints under the [Wan-AI](https://huggingface.co/Wan-AI) organization.
|
| 30 |
+
|
| 31 |
+
The following Wan models are supported in Diffusers:
|
| 32 |
+
- [Wan 2.1 T2V 1.3B](https://huggingface.co/Wan-AI/Wan2.1-T2V-1.3B-Diffusers)
|
| 33 |
+
- [Wan 2.1 T2V 14B](https://huggingface.co/Wan-AI/Wan2.1-T2V-14B-Diffusers)
|
| 34 |
+
- [Wan 2.1 I2V 14B - 480P](https://huggingface.co/Wan-AI/Wan2.1-I2V-14B-480P-Diffusers)
|
| 35 |
+
- [Wan 2.1 I2V 14B - 720P](https://huggingface.co/Wan-AI/Wan2.1-I2V-14B-720P-Diffusers)
|
| 36 |
+
- [Wan 2.1 FLF2V 14B - 720P](https://huggingface.co/Wan-AI/Wan2.1-FLF2V-14B-720P-diffusers)
|
| 37 |
+
- [Wan 2.1 VACE 1.3B](https://huggingface.co/Wan-AI/Wan2.1-VACE-1.3B-diffusers)
|
| 38 |
+
- [Wan 2.1 VACE 14B](https://huggingface.co/Wan-AI/Wan2.1-VACE-14B-diffusers)
|
| 39 |
+
|
| 40 |
+
> [!TIP]
|
| 41 |
+
> Click on the Wan2.1 models in the right sidebar for more examples of video generation.
|
| 42 |
+
|
| 43 |
+
### Text-to-Video Generation
|
| 44 |
+
|
| 45 |
+
The example below demonstrates how to generate a video from text optimized for memory or inference speed.
|
| 46 |
+
|
| 47 |
+
<hfoptions id="T2V usage">
|
| 48 |
+
<hfoption id="T2V memory">
|
| 49 |
+
|
| 50 |
+
Refer to the [Reduce memory usage](../../optimization/memory) guide for more details about the various memory saving techniques.
|
| 51 |
+
|
| 52 |
+
The Wan2.1 text-to-video model below requires ~13GB of VRAM.
|
| 53 |
+
|
| 54 |
+
```py
|
| 55 |
+
# pip install ftfy
|
| 56 |
+
import torch
|
| 57 |
+
import numpy as np
|
| 58 |
+
from diffusers import AutoModel, WanPipeline
|
| 59 |
+
from diffusers.quantizers import PipelineQuantizationConfig
|
| 60 |
+
from diffusers.hooks.group_offloading import apply_group_offloading
|
| 61 |
+
from diffusers.utils import export_to_video, load_image
|
| 62 |
+
from transformers import UMT5EncoderModel
|
| 63 |
+
|
| 64 |
+
text_encoder = UMT5EncoderModel.from_pretrained("Wan-AI/Wan2.1-T2V-14B-Diffusers", subfolder="text_encoder", torch_dtype=torch.bfloat16)
|
| 65 |
+
vae = AutoModel.from_pretrained("Wan-AI/Wan2.1-T2V-14B-Diffusers", subfolder="vae", torch_dtype=torch.float32)
|
| 66 |
+
transformer = AutoModel.from_pretrained("Wan-AI/Wan2.1-T2V-14B-Diffusers", subfolder="transformer", torch_dtype=torch.bfloat16)
|
| 67 |
+
|
| 68 |
+
# group-offloading
|
| 69 |
+
onload_device = torch.device("cuda")
|
| 70 |
+
offload_device = torch.device("cpu")
|
| 71 |
+
apply_group_offloading(text_encoder,
|
| 72 |
+
onload_device=onload_device,
|
| 73 |
+
offload_device=offload_device,
|
| 74 |
+
offload_type="block_level",
|
| 75 |
+
num_blocks_per_group=4
|
| 76 |
+
)
|
| 77 |
+
transformer.enable_group_offload(
|
| 78 |
+
onload_device=onload_device,
|
| 79 |
+
offload_device=offload_device,
|
| 80 |
+
offload_type="leaf_level",
|
| 81 |
+
use_stream=True
|
| 82 |
+
)
|
| 83 |
+
|
| 84 |
+
pipeline = WanPipeline.from_pretrained(
|
| 85 |
+
"Wan-AI/Wan2.1-T2V-14B-Diffusers",
|
| 86 |
+
vae=vae,
|
| 87 |
+
transformer=transformer,
|
| 88 |
+
text_encoder=text_encoder,
|
| 89 |
+
torch_dtype=torch.bfloat16
|
| 90 |
+
)
|
| 91 |
+
pipeline.to("cuda")
|
| 92 |
+
|
| 93 |
+
prompt = """
|
| 94 |
+
The camera rushes from far to near in a low-angle shot,
|
| 95 |
+
revealing a white ferret on a log. It plays, leaps into the water, and emerges, as the camera zooms in
|
| 96 |
+
for a close-up. Water splashes berry bushes nearby, while moss, snow, and leaves blanket the ground.
|
| 97 |
+
Birch trees and a light blue sky frame the scene, with ferns in the foreground. Side lighting casts dynamic
|
| 98 |
+
shadows and warm highlights. Medium composition, front view, low angle, with depth of field.
|
| 99 |
+
"""
|
| 100 |
+
negative_prompt = """
|
| 101 |
+
Bright tones, overexposed, static, blurred details, subtitles, style, works, paintings, images, static, overall gray, worst quality,
|
| 102 |
+
low quality, JPEG compression residue, ugly, incomplete, extra fingers, poorly drawn hands, poorly drawn faces, deformed, disfigured,
|
| 103 |
+
misshapen limbs, fused fingers, still picture, messy background, three legs, many people in the background, walking backwards
|
| 104 |
+
"""
|
| 105 |
+
|
| 106 |
+
output = pipeline(
|
| 107 |
+
prompt=prompt,
|
| 108 |
+
negative_prompt=negative_prompt,
|
| 109 |
+
num_frames=81,
|
| 110 |
+
guidance_scale=5.0,
|
| 111 |
+
).frames[0]
|
| 112 |
+
export_to_video(output, "output.mp4", fps=16)
|
| 113 |
+
```
|
| 114 |
+
|
| 115 |
+
</hfoption>
|
| 116 |
+
<hfoption id="T2V inference speed">
|
| 117 |
+
|
| 118 |
+
[Compilation](../../optimization/fp16#torchcompile) is slow the first time but subsequent calls to the pipeline are faster.
|
| 119 |
+
|
| 120 |
+
```py
|
| 121 |
+
# pip install ftfy
|
| 122 |
+
import torch
|
| 123 |
+
import numpy as np
|
| 124 |
+
from diffusers import AutoModel, WanPipeline
|
| 125 |
+
from diffusers.hooks.group_offloading import apply_group_offloading
|
| 126 |
+
from diffusers.utils import export_to_video, load_image
|
| 127 |
+
from transformers import UMT5EncoderModel
|
| 128 |
+
|
| 129 |
+
text_encoder = UMT5EncoderModel.from_pretrained("Wan-AI/Wan2.1-T2V-14B-Diffusers", subfolder="text_encoder", torch_dtype=torch.bfloat16)
|
| 130 |
+
vae = AutoModel.from_pretrained("Wan-AI/Wan2.1-T2V-14B-Diffusers", subfolder="vae", torch_dtype=torch.float32)
|
| 131 |
+
transformer = AutoModel.from_pretrained("Wan-AI/Wan2.1-T2V-14B-Diffusers", subfolder="transformer", torch_dtype=torch.bfloat16)
|
| 132 |
+
|
| 133 |
+
pipeline = WanPipeline.from_pretrained(
|
| 134 |
+
"Wan-AI/Wan2.1-T2V-14B-Diffusers",
|
| 135 |
+
vae=vae,
|
| 136 |
+
transformer=transformer,
|
| 137 |
+
text_encoder=text_encoder,
|
| 138 |
+
torch_dtype=torch.bfloat16
|
| 139 |
+
)
|
| 140 |
+
pipeline.to("cuda")
|
| 141 |
+
|
| 142 |
+
# torch.compile
|
| 143 |
+
pipeline.transformer.to(memory_format=torch.channels_last)
|
| 144 |
+
pipeline.transformer = torch.compile(
|
| 145 |
+
pipeline.transformer, mode="max-autotune", fullgraph=True
|
| 146 |
+
)
|
| 147 |
+
|
| 148 |
+
prompt = """
|
| 149 |
+
The camera rushes from far to near in a low-angle shot,
|
| 150 |
+
revealing a white ferret on a log. It plays, leaps into the water, and emerges, as the camera zooms in
|
| 151 |
+
for a close-up. Water splashes berry bushes nearby, while moss, snow, and leaves blanket the ground.
|
| 152 |
+
Birch trees and a light blue sky frame the scene, with ferns in the foreground. Side lighting casts dynamic
|
| 153 |
+
shadows and warm highlights. Medium composition, front view, low angle, with depth of field.
|
| 154 |
+
"""
|
| 155 |
+
negative_prompt = """
|
| 156 |
+
Bright tones, overexposed, static, blurred details, subtitles, style, works, paintings, images, static, overall gray, worst quality,
|
| 157 |
+
low quality, JPEG compression residue, ugly, incomplete, extra fingers, poorly drawn hands, poorly drawn faces, deformed, disfigured,
|
| 158 |
+
misshapen limbs, fused fingers, still picture, messy background, three legs, many people in the background, walking backwards
|
| 159 |
+
"""
|
| 160 |
+
|
| 161 |
+
output = pipeline(
|
| 162 |
+
prompt=prompt,
|
| 163 |
+
negative_prompt=negative_prompt,
|
| 164 |
+
num_frames=81,
|
| 165 |
+
guidance_scale=5.0,
|
| 166 |
+
).frames[0]
|
| 167 |
+
export_to_video(output, "output.mp4", fps=16)
|
| 168 |
+
```
|
| 169 |
+
|
| 170 |
+
</hfoption>
|
| 171 |
+
</hfoptions>
|
| 172 |
+
|
| 173 |
+
### First-Last-Frame-to-Video Generation
|
| 174 |
+
|
| 175 |
+
The example below demonstrates how to use the image-to-video pipeline to generate a video using a text description, a starting frame, and an ending frame.
|
| 176 |
+
|
| 177 |
+
<hfoptions id="FLF2V usage">
|
| 178 |
+
<hfoption id="usage">
|
| 179 |
+
|
| 180 |
+
```python
|
| 181 |
+
import numpy as np
|
| 182 |
+
import torch
|
| 183 |
+
import torchvision.transforms.functional as TF
|
| 184 |
+
from diffusers import AutoencoderKLWan, WanImageToVideoPipeline
|
| 185 |
+
from diffusers.utils import export_to_video, load_image
|
| 186 |
+
from transformers import CLIPVisionModel
|
| 187 |
+
|
| 188 |
+
|
| 189 |
+
model_id = "Wan-AI/Wan2.1-FLF2V-14B-720P-diffusers"
|
| 190 |
+
image_encoder = CLIPVisionModel.from_pretrained(model_id, subfolder="image_encoder", torch_dtype=torch.float32)
|
| 191 |
+
vae = AutoencoderKLWan.from_pretrained(model_id, subfolder="vae", torch_dtype=torch.float32)
|
| 192 |
+
pipe = WanImageToVideoPipeline.from_pretrained(
|
| 193 |
+
model_id, vae=vae, image_encoder=image_encoder, torch_dtype=torch.bfloat16
|
| 194 |
+
)
|
| 195 |
+
pipe.to("cuda")
|
| 196 |
+
|
| 197 |
+
first_frame = load_image("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/flf2v_input_first_frame.png")
|
| 198 |
+
last_frame = load_image("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/flf2v_input_last_frame.png")
|
| 199 |
+
|
| 200 |
+
def aspect_ratio_resize(image, pipe, max_area=720 * 1280):
|
| 201 |
+
aspect_ratio = image.height / image.width
|
| 202 |
+
mod_value = pipe.vae_scale_factor_spatial * pipe.transformer.config.patch_size[1]
|
| 203 |
+
height = round(np.sqrt(max_area * aspect_ratio)) // mod_value * mod_value
|
| 204 |
+
width = round(np.sqrt(max_area / aspect_ratio)) // mod_value * mod_value
|
| 205 |
+
image = image.resize((width, height))
|
| 206 |
+
return image, height, width
|
| 207 |
+
|
| 208 |
+
def center_crop_resize(image, height, width):
|
| 209 |
+
# Calculate resize ratio to match first frame dimensions
|
| 210 |
+
resize_ratio = max(width / image.width, height / image.height)
|
| 211 |
+
|
| 212 |
+
# Resize the image
|
| 213 |
+
width = round(image.width * resize_ratio)
|
| 214 |
+
height = round(image.height * resize_ratio)
|
| 215 |
+
size = [width, height]
|
| 216 |
+
image = TF.center_crop(image, size)
|
| 217 |
+
|
| 218 |
+
return image, height, width
|
| 219 |
+
|
| 220 |
+
first_frame, height, width = aspect_ratio_resize(first_frame, pipe)
|
| 221 |
+
if last_frame.size != first_frame.size:
|
| 222 |
+
last_frame, _, _ = center_crop_resize(last_frame, height, width)
|
| 223 |
+
|
| 224 |
+
prompt = "CG animation style, a small blue bird takes off from the ground, flapping its wings. The bird's feathers are delicate, with a unique pattern on its chest. The background shows a blue sky with white clouds under bright sunshine. The camera follows the bird upward, capturing its flight and the vastness of the sky from a close-up, low-angle perspective."
|
| 225 |
+
|
| 226 |
+
output = pipe(
|
| 227 |
+
image=first_frame, last_image=last_frame, prompt=prompt, height=height, width=width, guidance_scale=5.5
|
| 228 |
+
).frames[0]
|
| 229 |
+
export_to_video(output, "output.mp4", fps=16)
|
| 230 |
+
```
|
| 231 |
+
|
| 232 |
+
</hfoption>
|
| 233 |
+
</hfoptions>
|
| 234 |
+
|
| 235 |
+
### Any-to-Video Controllable Generation
|
| 236 |
+
|
| 237 |
+
Wan VACE supports various generation techniques which achieve controllable video generation. Some of the capabilities include:
|
| 238 |
+
- Control to Video (Depth, Pose, Sketch, Flow, Grayscale, Scribble, Layout, Boundary Box, etc.). Recommended library for preprocessing videos to obtain control videos: [huggingface/controlnet_aux]()
|
| 239 |
+
- Image/Video to Video (first frame, last frame, starting clip, ending clip, random clips)
|
| 240 |
+
- Inpainting and Outpainting
|
| 241 |
+
- Subject to Video (faces, object, characters, etc.)
|
| 242 |
+
- Composition to Video (reference anything, animate anything, swap anything, expand anything, move anything, etc.)
|
| 243 |
+
|
| 244 |
+
The code snippets available in [this](https://github.com/huggingface/diffusers/pull/11582) pull request demonstrate some examples of how videos can be generated with controllability signals.
|
| 245 |
+
|
| 246 |
+
The general rule of thumb to keep in mind when preparing inputs for the VACE pipeline is that the input images, or frames of a video that you want to use for conditioning, should have a corresponding mask that is black in color. The black mask signifies that the model will not generate new content for that area, and only use those parts for conditioning the generation process. For parts/frames that should be generated by the model, the mask should be white in color.
|
| 247 |
+
|
| 248 |
+
## Notes
|
| 249 |
+
|
| 250 |
+
- Wan2.1 supports LoRAs with [`~loaders.WanLoraLoaderMixin.load_lora_weights`].
|
| 251 |
+
|
| 252 |
+
<details>
|
| 253 |
+
<summary>Show example code</summary>
|
| 254 |
+
|
| 255 |
+
```py
|
| 256 |
+
# pip install ftfy
|
| 257 |
+
import torch
|
| 258 |
+
from diffusers import AutoModel, WanPipeline
|
| 259 |
+
from diffusers.schedulers.scheduling_unipc_multistep import UniPCMultistepScheduler
|
| 260 |
+
from diffusers.utils import export_to_video
|
| 261 |
+
|
| 262 |
+
vae = AutoModel.from_pretrained(
|
| 263 |
+
"Wan-AI/Wan2.1-T2V-1.3B-Diffusers", subfolder="vae", torch_dtype=torch.float32
|
| 264 |
+
)
|
| 265 |
+
pipeline = WanPipeline.from_pretrained(
|
| 266 |
+
"Wan-AI/Wan2.1-T2V-1.3B-Diffusers", vae=vae, torch_dtype=torch.bfloat16
|
| 267 |
+
)
|
| 268 |
+
pipeline.scheduler = UniPCMultistepScheduler.from_config(
|
| 269 |
+
pipeline.scheduler.config, flow_shift=5.0
|
| 270 |
+
)
|
| 271 |
+
pipeline.to("cuda")
|
| 272 |
+
|
| 273 |
+
pipeline.load_lora_weights("benjamin-paine/steamboat-willie-1.3b", adapter_name="steamboat-willie")
|
| 274 |
+
pipeline.set_adapters("steamboat-willie")
|
| 275 |
+
|
| 276 |
+
pipeline.enable_model_cpu_offload()
|
| 277 |
+
|
| 278 |
+
# use "steamboat willie style" to trigger the LoRA
|
| 279 |
+
prompt = """
|
| 280 |
+
steamboat willie style, golden era animation, The camera rushes from far to near in a low-angle shot,
|
| 281 |
+
revealing a white ferret on a log. It plays, leaps into the water, and emerges, as the camera zooms in
|
| 282 |
+
for a close-up. Water splashes berry bushes nearby, while moss, snow, and leaves blanket the ground.
|
| 283 |
+
Birch trees and a light blue sky frame the scene, with ferns in the foreground. Side lighting casts dynamic
|
| 284 |
+
shadows and warm highlights. Medium composition, front view, low angle, with depth of field.
|
| 285 |
+
"""
|
| 286 |
+
|
| 287 |
+
output = pipeline(
|
| 288 |
+
prompt=prompt,
|
| 289 |
+
num_frames=81,
|
| 290 |
+
guidance_scale=5.0,
|
| 291 |
+
).frames[0]
|
| 292 |
+
export_to_video(output, "output.mp4", fps=16)
|
| 293 |
+
```
|
| 294 |
+
|
| 295 |
+
</details>
|
| 296 |
+
|
| 297 |
+
- [`WanTransformer3DModel`] and [`AutoencoderKLWan`] supports loading from single files with [`~loaders.FromSingleFileMixin.from_single_file`].
|
| 298 |
+
|
| 299 |
+
<details>
|
| 300 |
+
<summary>Show example code</summary>
|
| 301 |
+
|
| 302 |
+
```py
|
| 303 |
+
# pip install ftfy
|
| 304 |
+
import torch
|
| 305 |
+
from diffusers import WanPipeline, AutoModel
|
| 306 |
+
|
| 307 |
+
vae = AutoModel.from_single_file(
|
| 308 |
+
"https://huggingface.co/Comfy-Org/Wan_2.1_ComfyUI_repackaged/blob/main/split_files/vae/wan_2.1_vae.safetensors"
|
| 309 |
+
)
|
| 310 |
+
transformer = AutoModel.from_single_file(
|
| 311 |
+
"https://huggingface.co/Comfy-Org/Wan_2.1_ComfyUI_repackaged/blob/main/split_files/diffusion_models/wan2.1_t2v_1.3B_bf16.safetensors",
|
| 312 |
+
torch_dtype=torch.bfloat16
|
| 313 |
+
)
|
| 314 |
+
pipeline = WanPipeline.from_pretrained(
|
| 315 |
+
"Wan-AI/Wan2.1-T2V-1.3B-Diffusers",
|
| 316 |
+
vae=vae,
|
| 317 |
+
transformer=transformer,
|
| 318 |
+
torch_dtype=torch.bfloat16
|
| 319 |
+
)
|
| 320 |
+
```
|
| 321 |
+
|
| 322 |
+
</details>
|
| 323 |
+
|
| 324 |
+
- Set the [`AutoencoderKLWan`] dtype to `torch.float32` for better decoding quality.
|
| 325 |
+
|
| 326 |
+
- The number of frames per second (fps) or `k` should be calculated by `4 * k + 1`.
|
| 327 |
+
|
| 328 |
+
- Try lower `shift` values (`2.0` to `5.0`) for lower resolution videos and higher `shift` values (`7.0` to `12.0`) for higher resolution images.
|
| 329 |
+
|
| 330 |
+
## WanPipeline
|
| 331 |
+
|
| 332 |
+
[[autodoc]] WanPipeline
|
| 333 |
+
- all
|
| 334 |
+
- __call__
|
| 335 |
+
|
| 336 |
+
## WanImageToVideoPipeline
|
| 337 |
+
|
| 338 |
+
[[autodoc]] WanImageToVideoPipeline
|
| 339 |
+
- all
|
| 340 |
+
- __call__
|
| 341 |
+
|
| 342 |
+
## WanVACEPipeline
|
| 343 |
+
|
| 344 |
+
[[autodoc]] WanVACEPipeline
|
| 345 |
+
- all
|
| 346 |
+
- __call__
|
| 347 |
+
|
| 348 |
+
## WanVideoToVideoPipeline
|
| 349 |
+
|
| 350 |
+
[[autodoc]] WanVideoToVideoPipeline
|
| 351 |
+
- all
|
| 352 |
+
- __call__
|
| 353 |
+
|
| 354 |
+
## WanPipelineOutput
|
| 355 |
+
|
| 356 |
+
[[autodoc]] pipelines.wan.pipeline_output.WanPipelineOutput
|
tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/pipelines/wuerstchen.md
ADDED
|
@@ -0,0 +1,167 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Würstchen
|
| 14 |
+
|
| 15 |
+
<div class="flex flex-wrap space-x-1">
|
| 16 |
+
<img alt="LoRA" src="https://img.shields.io/badge/LoRA-d8b4fe?style=flat"/>
|
| 17 |
+
</div>
|
| 18 |
+
|
| 19 |
+
<img src="https://github.com/dome272/Wuerstchen/assets/61938694/0617c863-165a-43ee-9303-2a17299a0cf9">
|
| 20 |
+
|
| 21 |
+
[Wuerstchen: An Efficient Architecture for Large-Scale Text-to-Image Diffusion Models](https://huggingface.co/papers/2306.00637) is by Pablo Pernias, Dominic Rampas, Mats L. Richter and Christopher Pal and Marc Aubreville.
|
| 22 |
+
|
| 23 |
+
The abstract from the paper is:
|
| 24 |
+
|
| 25 |
+
*We introduce Würstchen, a novel architecture for text-to-image synthesis that combines competitive performance with unprecedented cost-effectiveness for large-scale text-to-image diffusion models. A key contribution of our work is to develop a latent diffusion technique in which we learn a detailed but extremely compact semantic image representation used to guide the diffusion process. This highly compressed representation of an image provides much more detailed guidance compared to latent representations of language and this significantly reduces the computational requirements to achieve state-of-the-art results. Our approach also improves the quality of text-conditioned image generation based on our user preference study. The training requirements of our approach consists of 24,602 A100-GPU hours - compared to Stable Diffusion 2.1's 200,000 GPU hours. Our approach also requires less training data to achieve these results. Furthermore, our compact latent representations allows us to perform inference over twice as fast, slashing the usual costs and carbon footprint of a state-of-the-art (SOTA) diffusion model significantly, without compromising the end performance. In a broader comparison against SOTA models our approach is substantially more efficient and compares favorably in terms of image quality. We believe that this work motivates more emphasis on the prioritization of both performance and computational accessibility.*
|
| 26 |
+
|
| 27 |
+
## Würstchen Overview
|
| 28 |
+
Würstchen is a diffusion model, whose text-conditional model works in a highly compressed latent space of images. Why is this important? Compressing data can reduce computational costs for both training and inference by magnitudes. Training on 1024x1024 images is way more expensive than training on 32x32. Usually, other works make use of a relatively small compression, in the range of 4x - 8x spatial compression. Würstchen takes this to an extreme. Through its novel design, we achieve a 42x spatial compression. This was unseen before because common methods fail to faithfully reconstruct detailed images after 16x spatial compression. Würstchen employs a two-stage compression, what we call Stage A and Stage B. Stage A is a VQGAN, and Stage B is a Diffusion Autoencoder (more details can be found in the [paper](https://huggingface.co/papers/2306.00637)). A third model, Stage C, is learned in that highly compressed latent space. This training requires fractions of the compute used for current top-performing models, while also allowing cheaper and faster inference.
|
| 29 |
+
|
| 30 |
+
## Würstchen v2 comes to Diffusers
|
| 31 |
+
|
| 32 |
+
After the initial paper release, we have improved numerous things in the architecture, training and sampling, making Würstchen competitive to current state-of-the-art models in many ways. We are excited to release this new version together with Diffusers. Here is a list of the improvements.
|
| 33 |
+
|
| 34 |
+
- Higher resolution (1024x1024 up to 2048x2048)
|
| 35 |
+
- Faster inference
|
| 36 |
+
- Multi Aspect Resolution Sampling
|
| 37 |
+
- Better quality
|
| 38 |
+
|
| 39 |
+
|
| 40 |
+
We are releasing 3 checkpoints for the text-conditional image generation model (Stage C). Those are:
|
| 41 |
+
|
| 42 |
+
- v2-base
|
| 43 |
+
- v2-aesthetic
|
| 44 |
+
- **(default)** v2-interpolated (50% interpolation between v2-base and v2-aesthetic)
|
| 45 |
+
|
| 46 |
+
We recommend using v2-interpolated, as it has a nice touch of both photorealism and aesthetics. Use v2-base for finetunings as it does not have a style bias and use v2-aesthetic for very artistic generations.
|
| 47 |
+
A comparison can be seen here:
|
| 48 |
+
|
| 49 |
+
<img src="https://github.com/dome272/Wuerstchen/assets/61938694/2914830f-cbd3-461c-be64-d50734f4b49d" width=500>
|
| 50 |
+
|
| 51 |
+
## Text-to-Image Generation
|
| 52 |
+
|
| 53 |
+
For the sake of usability, Würstchen can be used with a single pipeline. This pipeline can be used as follows:
|
| 54 |
+
|
| 55 |
+
```python
|
| 56 |
+
import torch
|
| 57 |
+
from diffusers import AutoPipelineForText2Image
|
| 58 |
+
from diffusers.pipelines.wuerstchen import DEFAULT_STAGE_C_TIMESTEPS
|
| 59 |
+
|
| 60 |
+
pipe = AutoPipelineForText2Image.from_pretrained("warp-ai/wuerstchen", torch_dtype=torch.float16).to("cuda")
|
| 61 |
+
|
| 62 |
+
caption = "Anthropomorphic cat dressed as a fire fighter"
|
| 63 |
+
images = pipe(
|
| 64 |
+
caption,
|
| 65 |
+
width=1024,
|
| 66 |
+
height=1536,
|
| 67 |
+
prior_timesteps=DEFAULT_STAGE_C_TIMESTEPS,
|
| 68 |
+
prior_guidance_scale=4.0,
|
| 69 |
+
num_images_per_prompt=2,
|
| 70 |
+
).images
|
| 71 |
+
```
|
| 72 |
+
|
| 73 |
+
For explanation purposes, we can also initialize the two main pipelines of Würstchen individually. Würstchen consists of 3 stages: Stage C, Stage B, Stage A. They all have different jobs and work only together. When generating text-conditional images, Stage C will first generate the latents in a very compressed latent space. This is what happens in the `prior_pipeline`. Afterwards, the generated latents will be passed to Stage B, which decompresses the latents into a bigger latent space of a VQGAN. These latents can then be decoded by Stage A, which is a VQGAN, into the pixel-space. Stage B & Stage A are both encapsulated in the `decoder_pipeline`. For more details, take a look at the [paper](https://huggingface.co/papers/2306.00637).
|
| 74 |
+
|
| 75 |
+
```python
|
| 76 |
+
import torch
|
| 77 |
+
from diffusers import WuerstchenDecoderPipeline, WuerstchenPriorPipeline
|
| 78 |
+
from diffusers.pipelines.wuerstchen import DEFAULT_STAGE_C_TIMESTEPS
|
| 79 |
+
|
| 80 |
+
device = "cuda"
|
| 81 |
+
dtype = torch.float16
|
| 82 |
+
num_images_per_prompt = 2
|
| 83 |
+
|
| 84 |
+
prior_pipeline = WuerstchenPriorPipeline.from_pretrained(
|
| 85 |
+
"warp-ai/wuerstchen-prior", torch_dtype=dtype
|
| 86 |
+
).to(device)
|
| 87 |
+
decoder_pipeline = WuerstchenDecoderPipeline.from_pretrained(
|
| 88 |
+
"warp-ai/wuerstchen", torch_dtype=dtype
|
| 89 |
+
).to(device)
|
| 90 |
+
|
| 91 |
+
caption = "Anthropomorphic cat dressed as a fire fighter"
|
| 92 |
+
negative_prompt = ""
|
| 93 |
+
|
| 94 |
+
prior_output = prior_pipeline(
|
| 95 |
+
prompt=caption,
|
| 96 |
+
height=1024,
|
| 97 |
+
width=1536,
|
| 98 |
+
timesteps=DEFAULT_STAGE_C_TIMESTEPS,
|
| 99 |
+
negative_prompt=negative_prompt,
|
| 100 |
+
guidance_scale=4.0,
|
| 101 |
+
num_images_per_prompt=num_images_per_prompt,
|
| 102 |
+
)
|
| 103 |
+
decoder_output = decoder_pipeline(
|
| 104 |
+
image_embeddings=prior_output.image_embeddings,
|
| 105 |
+
prompt=caption,
|
| 106 |
+
negative_prompt=negative_prompt,
|
| 107 |
+
guidance_scale=0.0,
|
| 108 |
+
output_type="pil",
|
| 109 |
+
).images[0]
|
| 110 |
+
decoder_output
|
| 111 |
+
```
|
| 112 |
+
|
| 113 |
+
## Speed-Up Inference
|
| 114 |
+
You can make use of `torch.compile` function and gain a speed-up of about 2-3x:
|
| 115 |
+
|
| 116 |
+
```python
|
| 117 |
+
prior_pipeline.prior = torch.compile(prior_pipeline.prior, mode="reduce-overhead", fullgraph=True)
|
| 118 |
+
decoder_pipeline.decoder = torch.compile(decoder_pipeline.decoder, mode="reduce-overhead", fullgraph=True)
|
| 119 |
+
```
|
| 120 |
+
|
| 121 |
+
## Limitations
|
| 122 |
+
|
| 123 |
+
- Due to the high compression employed by Würstchen, generations can lack a good amount
|
| 124 |
+
of detail. To our human eye, this is especially noticeable in faces, hands etc.
|
| 125 |
+
- **Images can only be generated in 128-pixel steps**, e.g. the next higher resolution
|
| 126 |
+
after 1024x1024 is 1152x1152
|
| 127 |
+
- The model lacks the ability to render correct text in images
|
| 128 |
+
- The model often does not achieve photorealism
|
| 129 |
+
- Difficult compositional prompts are hard for the model
|
| 130 |
+
|
| 131 |
+
The original codebase, as well as experimental ideas, can be found at [dome272/Wuerstchen](https://github.com/dome272/Wuerstchen).
|
| 132 |
+
|
| 133 |
+
|
| 134 |
+
## WuerstchenCombinedPipeline
|
| 135 |
+
|
| 136 |
+
[[autodoc]] WuerstchenCombinedPipeline
|
| 137 |
+
- all
|
| 138 |
+
- __call__
|
| 139 |
+
|
| 140 |
+
## WuerstchenPriorPipeline
|
| 141 |
+
|
| 142 |
+
[[autodoc]] WuerstchenPriorPipeline
|
| 143 |
+
- all
|
| 144 |
+
- __call__
|
| 145 |
+
|
| 146 |
+
## WuerstchenPriorPipelineOutput
|
| 147 |
+
|
| 148 |
+
[[autodoc]] pipelines.wuerstchen.pipeline_wuerstchen_prior.WuerstchenPriorPipelineOutput
|
| 149 |
+
|
| 150 |
+
## WuerstchenDecoderPipeline
|
| 151 |
+
|
| 152 |
+
[[autodoc]] WuerstchenDecoderPipeline
|
| 153 |
+
- all
|
| 154 |
+
- __call__
|
| 155 |
+
|
| 156 |
+
## Citation
|
| 157 |
+
|
| 158 |
+
```bibtex
|
| 159 |
+
@misc{pernias2023wuerstchen,
|
| 160 |
+
title={Wuerstchen: An Efficient Architecture for Large-Scale Text-to-Image Diffusion Models},
|
| 161 |
+
author={Pablo Pernias and Dominic Rampas and Mats L. Richter and Christopher J. Pal and Marc Aubreville},
|
| 162 |
+
year={2023},
|
| 163 |
+
eprint={2306.00637},
|
| 164 |
+
archivePrefix={arXiv},
|
| 165 |
+
primaryClass={cs.CV}
|
| 166 |
+
}
|
| 167 |
+
```
|
tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/quantization.md
ADDED
|
@@ -0,0 +1,46 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
|
| 12 |
+
-->
|
| 13 |
+
|
| 14 |
+
# Quantization
|
| 15 |
+
|
| 16 |
+
Quantization techniques reduce memory and computational costs by representing weights and activations with lower-precision data types like 8-bit integers (int8). This enables loading larger models you normally wouldn't be able to fit into memory, and speeding up inference.
|
| 17 |
+
|
| 18 |
+
<Tip>
|
| 19 |
+
|
| 20 |
+
Learn how to quantize models in the [Quantization](../quantization/overview) guide.
|
| 21 |
+
|
| 22 |
+
</Tip>
|
| 23 |
+
|
| 24 |
+
## PipelineQuantizationConfig
|
| 25 |
+
|
| 26 |
+
[[autodoc]] quantizers.PipelineQuantizationConfig
|
| 27 |
+
|
| 28 |
+
## BitsAndBytesConfig
|
| 29 |
+
|
| 30 |
+
[[autodoc]] BitsAndBytesConfig
|
| 31 |
+
|
| 32 |
+
## GGUFQuantizationConfig
|
| 33 |
+
|
| 34 |
+
[[autodoc]] GGUFQuantizationConfig
|
| 35 |
+
|
| 36 |
+
## QuantoConfig
|
| 37 |
+
|
| 38 |
+
[[autodoc]] QuantoConfig
|
| 39 |
+
|
| 40 |
+
## TorchAoConfig
|
| 41 |
+
|
| 42 |
+
[[autodoc]] TorchAoConfig
|
| 43 |
+
|
| 44 |
+
## DiffusersQuantizer
|
| 45 |
+
|
| 46 |
+
[[autodoc]] quantizers.base.DiffusersQuantizer
|
tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/schedulers/cm_stochastic_iterative.md
ADDED
|
@@ -0,0 +1,27 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# CMStochasticIterativeScheduler
|
| 14 |
+
|
| 15 |
+
[Consistency Models](https://huggingface.co/papers/2303.01469) by Yang Song, Prafulla Dhariwal, Mark Chen, and Ilya Sutskever introduced a multistep and onestep scheduler (Algorithm 1) that is capable of generating good samples in one or a small number of steps.
|
| 16 |
+
|
| 17 |
+
The abstract from the paper is:
|
| 18 |
+
|
| 19 |
+
*Diffusion models have significantly advanced the fields of image, audio, and video generation, but they depend on an iterative sampling process that causes slow generation. To overcome this limitation, we propose consistency models, a new family of models that generate high quality samples by directly mapping noise to data. They support fast one-step generation by design, while still allowing multistep sampling to trade compute for sample quality. They also support zero-shot data editing, such as image inpainting, colorization, and super-resolution, without requiring explicit training on these tasks. Consistency models can be trained either by distilling pre-trained diffusion models, or as standalone generative models altogether. Through extensive experiments, we demonstrate that they outperform existing distillation techniques for diffusion models in one- and few-step sampling, achieving the new state-of-the-art FID of 3.55 on CIFAR-10 and 6.20 on ImageNet 64x64 for one-step generation. When trained in isolation, consistency models become a new family of generative models that can outperform existing one-step, non-adversarial generative models on standard benchmarks such as CIFAR-10, ImageNet 64x64 and LSUN 256x256.*
|
| 20 |
+
|
| 21 |
+
The original codebase can be found at [openai/consistency_models](https://github.com/openai/consistency_models).
|
| 22 |
+
|
| 23 |
+
## CMStochasticIterativeScheduler
|
| 24 |
+
[[autodoc]] CMStochasticIterativeScheduler
|
| 25 |
+
|
| 26 |
+
## CMStochasticIterativeSchedulerOutput
|
| 27 |
+
[[autodoc]] schedulers.scheduling_consistency_models.CMStochasticIterativeSchedulerOutput
|
tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/schedulers/consistency_decoder.md
ADDED
|
@@ -0,0 +1,21 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# ConsistencyDecoderScheduler
|
| 14 |
+
|
| 15 |
+
This scheduler is a part of the [`ConsistencyDecoderPipeline`] and was introduced in [DALL-E 3](https://openai.com/dall-e-3).
|
| 16 |
+
|
| 17 |
+
The original codebase can be found at [openai/consistency_models](https://github.com/openai/consistency_models).
|
| 18 |
+
|
| 19 |
+
|
| 20 |
+
## ConsistencyDecoderScheduler
|
| 21 |
+
[[autodoc]] schedulers.scheduling_consistency_decoder.ConsistencyDecoderScheduler
|
tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/schedulers/cosine_dpm.md
ADDED
|
@@ -0,0 +1,24 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# CosineDPMSolverMultistepScheduler
|
| 14 |
+
|
| 15 |
+
The [`CosineDPMSolverMultistepScheduler`] is a variant of [`DPMSolverMultistepScheduler`] with cosine schedule, proposed by Nichol and Dhariwal (2021).
|
| 16 |
+
It is being used in the [Stable Audio Open](https://huggingface.co/papers/2407.14358) paper and the [Stability-AI/stable-audio-tool](https://github.com/Stability-AI/stable-audio-tools) codebase.
|
| 17 |
+
|
| 18 |
+
This scheduler was contributed by [Yoach Lacombe](https://huggingface.co/ylacombe).
|
| 19 |
+
|
| 20 |
+
## CosineDPMSolverMultistepScheduler
|
| 21 |
+
[[autodoc]] CosineDPMSolverMultistepScheduler
|
| 22 |
+
|
| 23 |
+
## SchedulerOutput
|
| 24 |
+
[[autodoc]] schedulers.scheduling_utils.SchedulerOutput
|
tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/schedulers/ddim.md
ADDED
|
@@ -0,0 +1,82 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# DDIMScheduler
|
| 14 |
+
|
| 15 |
+
[Denoising Diffusion Implicit Models](https://huggingface.co/papers/2010.02502) (DDIM) by Jiaming Song, Chenlin Meng and Stefano Ermon.
|
| 16 |
+
|
| 17 |
+
The abstract from the paper is:
|
| 18 |
+
|
| 19 |
+
*Denoising diffusion probabilistic models (DDPMs) have achieved high quality image generation without adversarial training, yet they require simulating a Markov chain for many steps to produce a sample.
|
| 20 |
+
To accelerate sampling, we present denoising diffusion implicit models (DDIMs), a more efficient class of iterative implicit probabilistic models
|
| 21 |
+
with the same training procedure as DDPMs. In DDPMs, the generative process is defined as the reverse of a Markovian diffusion process.
|
| 22 |
+
We construct a class of non-Markovian diffusion processes that lead to the same training objective, but whose reverse process can be much faster to sample from.
|
| 23 |
+
We empirically demonstrate that DDIMs can produce high quality samples 10× to 50× faster in terms of wall-clock time compared to DDPMs, allow us to trade off computation for sample quality, and can perform semantically meaningful image interpolation directly in the latent space.*
|
| 24 |
+
|
| 25 |
+
The original codebase of this paper can be found at [ermongroup/ddim](https://github.com/ermongroup/ddim), and you can contact the author on [tsong.me](https://tsong.me/).
|
| 26 |
+
|
| 27 |
+
## Tips
|
| 28 |
+
|
| 29 |
+
The paper [Common Diffusion Noise Schedules and Sample Steps are Flawed](https://huggingface.co/papers/2305.08891) claims that a mismatch between the training and inference settings leads to suboptimal inference generation results for Stable Diffusion. To fix this, the authors propose:
|
| 30 |
+
|
| 31 |
+
<Tip warning={true}>
|
| 32 |
+
|
| 33 |
+
🧪 This is an experimental feature!
|
| 34 |
+
|
| 35 |
+
</Tip>
|
| 36 |
+
|
| 37 |
+
1. rescale the noise schedule to enforce zero terminal signal-to-noise ratio (SNR)
|
| 38 |
+
|
| 39 |
+
```py
|
| 40 |
+
pipe.scheduler = DDIMScheduler.from_config(pipe.scheduler.config, rescale_betas_zero_snr=True)
|
| 41 |
+
```
|
| 42 |
+
|
| 43 |
+
2. train a model with `v_prediction` (add the following argument to the [train_text_to_image.py](https://github.com/huggingface/diffusers/blob/main/examples/text_to_image/train_text_to_image.py) or [train_text_to_image_lora.py](https://github.com/huggingface/diffusers/blob/main/examples/text_to_image/train_text_to_image_lora.py) scripts)
|
| 44 |
+
|
| 45 |
+
```bash
|
| 46 |
+
--prediction_type="v_prediction"
|
| 47 |
+
```
|
| 48 |
+
|
| 49 |
+
3. change the sampler to always start from the last timestep
|
| 50 |
+
|
| 51 |
+
```py
|
| 52 |
+
pipe.scheduler = DDIMScheduler.from_config(pipe.scheduler.config, timestep_spacing="trailing")
|
| 53 |
+
```
|
| 54 |
+
|
| 55 |
+
4. rescale classifier-free guidance to prevent over-exposure
|
| 56 |
+
|
| 57 |
+
```py
|
| 58 |
+
image = pipe(prompt, guidance_rescale=0.7).images[0]
|
| 59 |
+
```
|
| 60 |
+
|
| 61 |
+
For example:
|
| 62 |
+
|
| 63 |
+
```py
|
| 64 |
+
from diffusers import DiffusionPipeline, DDIMScheduler
|
| 65 |
+
import torch
|
| 66 |
+
|
| 67 |
+
pipe = DiffusionPipeline.from_pretrained("ptx0/pseudo-journey-v2", torch_dtype=torch.float16)
|
| 68 |
+
pipe.scheduler = DDIMScheduler.from_config(
|
| 69 |
+
pipe.scheduler.config, rescale_betas_zero_snr=True, timestep_spacing="trailing"
|
| 70 |
+
)
|
| 71 |
+
pipe.to("cuda")
|
| 72 |
+
|
| 73 |
+
prompt = "A lion in galaxies, spirals, nebulae, stars, smoke, iridescent, intricate detail, octane render, 8k"
|
| 74 |
+
image = pipe(prompt, guidance_rescale=0.7).images[0]
|
| 75 |
+
image
|
| 76 |
+
```
|
| 77 |
+
|
| 78 |
+
## DDIMScheduler
|
| 79 |
+
[[autodoc]] DDIMScheduler
|
| 80 |
+
|
| 81 |
+
## DDIMSchedulerOutput
|
| 82 |
+
[[autodoc]] schedulers.scheduling_ddim.DDIMSchedulerOutput
|
tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/schedulers/ddim_cogvideox.md
ADDED
|
@@ -0,0 +1,19 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# CogVideoXDDIMScheduler
|
| 14 |
+
|
| 15 |
+
`CogVideoXDDIMScheduler` is based on [Denoising Diffusion Implicit Models](https://huggingface.co/papers/2010.02502), specifically for CogVideoX models.
|
| 16 |
+
|
| 17 |
+
## CogVideoXDDIMScheduler
|
| 18 |
+
|
| 19 |
+
[[autodoc]] CogVideoXDDIMScheduler
|
tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/schedulers/ddim_inverse.md
ADDED
|
@@ -0,0 +1,19 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# DDIMInverseScheduler
|
| 14 |
+
|
| 15 |
+
`DDIMInverseScheduler` is the inverted scheduler from [Denoising Diffusion Implicit Models](https://huggingface.co/papers/2010.02502) (DDIM) by Jiaming Song, Chenlin Meng and Stefano Ermon.
|
| 16 |
+
The implementation is mostly based on the DDIM inversion definition from [Null-text Inversion for Editing Real Images using Guided Diffusion Models](https://huggingface.co/papers/2211.09794).
|
| 17 |
+
|
| 18 |
+
## DDIMInverseScheduler
|
| 19 |
+
[[autodoc]] DDIMInverseScheduler
|
tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/schedulers/ddpm.md
ADDED
|
@@ -0,0 +1,25 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# DDPMScheduler
|
| 14 |
+
|
| 15 |
+
[Denoising Diffusion Probabilistic Models](https://huggingface.co/papers/2006.11239) (DDPM) by Jonathan Ho, Ajay Jain and Pieter Abbeel proposes a diffusion based model of the same name. In the context of the 🤗 Diffusers library, DDPM refers to the discrete denoising scheduler from the paper as well as the pipeline.
|
| 16 |
+
|
| 17 |
+
The abstract from the paper is:
|
| 18 |
+
|
| 19 |
+
*We present high quality image synthesis results using diffusion probabilistic models, a class of latent variable models inspired by considerations from nonequilibrium thermodynamics. Our best results are obtained by training on a weighted variational bound designed according to a novel connection between diffusion probabilistic models and denoising score matching with Langevin dynamics, and our models naturally admit a progressive lossy decompression scheme that can be interpreted as a generalization of autoregressive decoding. On the unconditional CIFAR10 dataset, we obtain an Inception score of 9.46 and a state-of-the-art FID score of 3.17. On 256x256 LSUN, we obtain sample quality similar to ProgressiveGAN. Our implementation is available at [this https URL](https://github.com/hojonathanho/diffusion).*
|
| 20 |
+
|
| 21 |
+
## DDPMScheduler
|
| 22 |
+
[[autodoc]] DDPMScheduler
|
| 23 |
+
|
| 24 |
+
## DDPMSchedulerOutput
|
| 25 |
+
[[autodoc]] schedulers.scheduling_ddpm.DDPMSchedulerOutput
|
tasks/tasksmith-9ca70b8463d4/tests/source/docs/source/en/api/schedulers/deis.md
ADDED
|
@@ -0,0 +1,34 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# DEISMultistepScheduler
|
| 14 |
+
|
| 15 |
+
Diffusion Exponential Integrator Sampler (DEIS) is proposed in [Fast Sampling of Diffusion Models with Exponential Integrator](https://huggingface.co/papers/2204.13902) by Qinsheng Zhang and Yongxin Chen. `DEISMultistepScheduler` is a fast high order solver for diffusion ordinary differential equations (ODEs).
|
| 16 |
+
|
| 17 |
+
This implementation modifies the polynomial fitting formula in log-rho space instead of the original linear `t` space in the DEIS paper. The modification enjoys closed-form coefficients for exponential multistep update instead of replying on the numerical solver.
|
| 18 |
+
|
| 19 |
+
The abstract from the paper is:
|
| 20 |
+
|
| 21 |
+
*The past few years have witnessed the great success of Diffusion models~(DMs) in generating high-fidelity samples in generative modeling tasks. A major limitation of the DM is its notoriously slow sampling procedure which normally requires hundreds to thousands of time discretization steps of the learned diffusion process to reach the desired accuracy. Our goal is to develop a fast sampling method for DMs with a much less number of steps while retaining high sample quality. To this end, we systematically analyze the sampling procedure in DMs and identify key factors that affect the sample quality, among which the method of discretization is most crucial. By carefully examining the learned diffusion process, we propose Diffusion Exponential Integrator Sampler~(DEIS). It is based on the Exponential Integrator designed for discretizing ordinary differential equations (ODEs) and leverages a semilinear structure of the learned diffusion process to reduce the discretization error. The proposed method can be applied to any DMs and can generate high-fidelity samples in as few as 10 steps. In our experiments, it takes about 3 minutes on one A6000 GPU to generate 50k images from CIFAR10. Moreover, by directly using pre-trained DMs, we achieve the state-of-art sampling performance when the number of score function evaluation~(NFE) is limited, e.g., 4.17 FID with 10 NFEs, 3.37 FID, and 9.74 IS with only 15 NFEs on CIFAR10. Code is available at [this https URL](https://github.com/qsh-zh/deis).*
|
| 22 |
+
|
| 23 |
+
## Tips
|
| 24 |
+
|
| 25 |
+
It is recommended to set `solver_order` to 2 or 3, while `solver_order=1` is equivalent to [`DDIMScheduler`].
|
| 26 |
+
|
| 27 |
+
Dynamic thresholding from [Imagen](https://huggingface.co/papers/2205.11487) is supported, and for pixel-space
|
| 28 |
+
diffusion models, you can set `thresholding=True` to use the dynamic thresholding.
|
| 29 |
+
|
| 30 |
+
## DEISMultistepScheduler
|
| 31 |
+
[[autodoc]] DEISMultistepScheduler
|
| 32 |
+
|
| 33 |
+
## SchedulerOutput
|
| 34 |
+
[[autodoc]] schedulers.scheduling_utils.SchedulerOutput
|