


Stage Harbor release files 74501-75000
Browse filesThis view is limited to 50 files because it contains too many changes. See raw diff
- tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/consistency_decoder.md +21 -0
- tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/cosine_dpm.md +24 -0
- tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/ddim.md +79 -0
- tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/ddim_cogvideox.md +19 -0
- tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/ddim_inverse.md +19 -0
- tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/ddpm.md +25 -0
- tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/deis.md +34 -0
- tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/dpm_discrete.md +23 -0
- tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/dpm_discrete_ancestral.md +23 -0
- tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/dpm_sde.md +21 -0
- tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/edm_euler.md +22 -0
- tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/edm_multistep_dpm_solver.md +24 -0
- tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/euler.md +22 -0
- tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/euler_ancestral.md +21 -0
- tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/flow_match_euler_discrete.md +18 -0
- tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/flow_match_heun_discrete.md +18 -0
- tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/heun.md +21 -0
- tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/ipndm.md +21 -0
- tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/lcm.md +21 -0
- tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/lms_discrete.md +21 -0
- tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/multistep_dpm_solver.md +35 -0
- tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/multistep_dpm_solver_cogvideox.md +19 -0
- tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/multistep_dpm_solver_inverse.md +30 -0
- tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/overview.md +73 -0
- tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/pndm.md +21 -0
- tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/repaint.md +27 -0
- tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/score_sde_ve.md +25 -0
- tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/score_sde_vp.md +25 -0
- tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/singlestep_dpm_solver.md +35 -0
- tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/stochastic_karras_ve.md +21 -0
- tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/tcd.md +29 -0
- tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/unipc.md +35 -0
- tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/vq_diffusion.md +25 -0
- tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/utilities.md +55 -0
- tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/video_processor.md +21 -0
- tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/community_projects.md +90 -0
- tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/conceptual/contribution.md +568 -0
- tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/conceptual/ethical_guidelines.md +63 -0
- tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/conceptual/evaluation.md +566 -0
- tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/conceptual/philosophy.md +110 -0
- tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/hybrid_inference/api_reference.md +11 -0
- tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/hybrid_inference/overview.md +305 -0
- tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/imgs/access_request.png +3 -0
- tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/imgs/diffusers_library.jpg +3 -0
- tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/index.md +35 -0
- tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/installation.md +146 -0
- tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/modular_diffusers/auto_pipeline_blocks.md +225 -0
- tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/modular_diffusers/components_manager.md +96 -0
- tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/modular_diffusers/custom_blocks.md +335 -0
- tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/modular_diffusers/guiders.md +161 -0
tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/consistency_decoder.md
ADDED
|
@@ -0,0 +1,21 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# ConsistencyDecoderScheduler
|
| 14 |
+
|
| 15 |
+
This scheduler is a part of the [`ConsistencyDecoderPipeline`] and was introduced in [DALL-E 3](https://openai.com/dall-e-3).
|
| 16 |
+
|
| 17 |
+
The original codebase can be found at [openai/consistency_models](https://github.com/openai/consistency_models).
|
| 18 |
+
|
| 19 |
+
|
| 20 |
+
## ConsistencyDecoderScheduler
|
| 21 |
+
[[autodoc]] schedulers.scheduling_consistency_decoder.ConsistencyDecoderScheduler
|
tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/cosine_dpm.md
ADDED
|
@@ -0,0 +1,24 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# CosineDPMSolverMultistepScheduler
|
| 14 |
+
|
| 15 |
+
The [`CosineDPMSolverMultistepScheduler`] is a variant of [`DPMSolverMultistepScheduler`] with cosine schedule, proposed by Nichol and Dhariwal (2021).
|
| 16 |
+
It is being used in the [Stable Audio Open](https://huggingface.co/papers/2407.14358) paper and the [Stability-AI/stable-audio-tool](https://github.com/Stability-AI/stable-audio-tools) codebase.
|
| 17 |
+
|
| 18 |
+
This scheduler was contributed by [Yoach Lacombe](https://huggingface.co/ylacombe).
|
| 19 |
+
|
| 20 |
+
## CosineDPMSolverMultistepScheduler
|
| 21 |
+
[[autodoc]] CosineDPMSolverMultistepScheduler
|
| 22 |
+
|
| 23 |
+
## SchedulerOutput
|
| 24 |
+
[[autodoc]] schedulers.scheduling_utils.SchedulerOutput
|
tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/ddim.md
ADDED
|
@@ -0,0 +1,79 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# DDIMScheduler
|
| 14 |
+
|
| 15 |
+
[Denoising Diffusion Implicit Models](https://huggingface.co/papers/2010.02502) (DDIM) by Jiaming Song, Chenlin Meng and Stefano Ermon.
|
| 16 |
+
|
| 17 |
+
The abstract from the paper is:
|
| 18 |
+
|
| 19 |
+
*Denoising diffusion probabilistic models (DDPMs) have achieved high quality image generation without adversarial training, yet they require simulating a Markov chain for many steps to produce a sample.
|
| 20 |
+
To accelerate sampling, we present denoising diffusion implicit models (DDIMs), a more efficient class of iterative implicit probabilistic models
|
| 21 |
+
with the same training procedure as DDPMs. In DDPMs, the generative process is defined as the reverse of a Markovian diffusion process.
|
| 22 |
+
We construct a class of non-Markovian diffusion processes that lead to the same training objective, but whose reverse process can be much faster to sample from.
|
| 23 |
+
We empirically demonstrate that DDIMs can produce high quality samples 10× to 50× faster in terms of wall-clock time compared to DDPMs, allow us to trade off computation for sample quality, and can perform semantically meaningful image interpolation directly in the latent space.*
|
| 24 |
+
|
| 25 |
+
The original codebase of this paper can be found at [ermongroup/ddim](https://github.com/ermongroup/ddim), and you can contact the author on [tsong.me](https://tsong.me/).
|
| 26 |
+
|
| 27 |
+
## Tips
|
| 28 |
+
|
| 29 |
+
The paper [Common Diffusion Noise Schedules and Sample Steps are Flawed](https://huggingface.co/papers/2305.08891) claims that a mismatch between the training and inference settings leads to suboptimal inference generation results for Stable Diffusion. To fix this, the authors propose:
|
| 30 |
+
|
| 31 |
+
> [!WARNING]
|
| 32 |
+
> 🧪 This is an experimental feature!
|
| 33 |
+
|
| 34 |
+
1. rescale the noise schedule to enforce zero terminal signal-to-noise ratio (SNR)
|
| 35 |
+
|
| 36 |
+
```py
|
| 37 |
+
pipe.scheduler = DDIMScheduler.from_config(pipe.scheduler.config, rescale_betas_zero_snr=True)
|
| 38 |
+
```
|
| 39 |
+
|
| 40 |
+
2. train a model with `v_prediction` (add the following argument to the [train_text_to_image.py](https://github.com/huggingface/diffusers/blob/main/examples/text_to_image/train_text_to_image.py) or [train_text_to_image_lora.py](https://github.com/huggingface/diffusers/blob/main/examples/text_to_image/train_text_to_image_lora.py) scripts)
|
| 41 |
+
|
| 42 |
+
```bash
|
| 43 |
+
--prediction_type="v_prediction"
|
| 44 |
+
```
|
| 45 |
+
|
| 46 |
+
3. change the sampler to always start from the last timestep
|
| 47 |
+
|
| 48 |
+
```py
|
| 49 |
+
pipe.scheduler = DDIMScheduler.from_config(pipe.scheduler.config, timestep_spacing="trailing")
|
| 50 |
+
```
|
| 51 |
+
|
| 52 |
+
4. rescale classifier-free guidance to prevent over-exposure
|
| 53 |
+
|
| 54 |
+
```py
|
| 55 |
+
image = pipe(prompt, guidance_rescale=0.7).images[0]
|
| 56 |
+
```
|
| 57 |
+
|
| 58 |
+
For example:
|
| 59 |
+
|
| 60 |
+
```py
|
| 61 |
+
from diffusers import DiffusionPipeline, DDIMScheduler
|
| 62 |
+
import torch
|
| 63 |
+
|
| 64 |
+
pipe = DiffusionPipeline.from_pretrained("ptx0/pseudo-journey-v2", torch_dtype=torch.float16)
|
| 65 |
+
pipe.scheduler = DDIMScheduler.from_config(
|
| 66 |
+
pipe.scheduler.config, rescale_betas_zero_snr=True, timestep_spacing="trailing"
|
| 67 |
+
)
|
| 68 |
+
pipe.to("cuda")
|
| 69 |
+
|
| 70 |
+
prompt = "A lion in galaxies, spirals, nebulae, stars, smoke, iridescent, intricate detail, octane render, 8k"
|
| 71 |
+
image = pipe(prompt, guidance_rescale=0.7).images[0]
|
| 72 |
+
image
|
| 73 |
+
```
|
| 74 |
+
|
| 75 |
+
## DDIMScheduler
|
| 76 |
+
[[autodoc]] DDIMScheduler
|
| 77 |
+
|
| 78 |
+
## DDIMSchedulerOutput
|
| 79 |
+
[[autodoc]] schedulers.scheduling_ddim.DDIMSchedulerOutput
|
tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/ddim_cogvideox.md
ADDED
|
@@ -0,0 +1,19 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# CogVideoXDDIMScheduler
|
| 14 |
+
|
| 15 |
+
`CogVideoXDDIMScheduler` is based on [Denoising Diffusion Implicit Models](https://huggingface.co/papers/2010.02502), specifically for CogVideoX models.
|
| 16 |
+
|
| 17 |
+
## CogVideoXDDIMScheduler
|
| 18 |
+
|
| 19 |
+
[[autodoc]] CogVideoXDDIMScheduler
|
tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/ddim_inverse.md
ADDED
|
@@ -0,0 +1,19 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# DDIMInverseScheduler
|
| 14 |
+
|
| 15 |
+
`DDIMInverseScheduler` is the inverted scheduler from [Denoising Diffusion Implicit Models](https://huggingface.co/papers/2010.02502) (DDIM) by Jiaming Song, Chenlin Meng and Stefano Ermon.
|
| 16 |
+
The implementation is mostly based on the DDIM inversion definition from [Null-text Inversion for Editing Real Images using Guided Diffusion Models](https://huggingface.co/papers/2211.09794).
|
| 17 |
+
|
| 18 |
+
## DDIMInverseScheduler
|
| 19 |
+
[[autodoc]] DDIMInverseScheduler
|
tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/ddpm.md
ADDED
|
@@ -0,0 +1,25 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# DDPMScheduler
|
| 14 |
+
|
| 15 |
+
[Denoising Diffusion Probabilistic Models](https://huggingface.co/papers/2006.11239) (DDPM) by Jonathan Ho, Ajay Jain and Pieter Abbeel proposes a diffusion based model of the same name. In the context of the 🤗 Diffusers library, DDPM refers to the discrete denoising scheduler from the paper as well as the pipeline.
|
| 16 |
+
|
| 17 |
+
The abstract from the paper is:
|
| 18 |
+
|
| 19 |
+
*We present high quality image synthesis results using diffusion probabilistic models, a class of latent variable models inspired by considerations from nonequilibrium thermodynamics. Our best results are obtained by training on a weighted variational bound designed according to a novel connection between diffusion probabilistic models and denoising score matching with Langevin dynamics, and our models naturally admit a progressive lossy decompression scheme that can be interpreted as a generalization of autoregressive decoding. On the unconditional CIFAR10 dataset, we obtain an Inception score of 9.46 and a state-of-the-art FID score of 3.17. On 256x256 LSUN, we obtain sample quality similar to ProgressiveGAN. Our implementation is available at [this https URL](https://github.com/hojonathanho/diffusion).*
|
| 20 |
+
|
| 21 |
+
## DDPMScheduler
|
| 22 |
+
[[autodoc]] DDPMScheduler
|
| 23 |
+
|
| 24 |
+
## DDPMSchedulerOutput
|
| 25 |
+
[[autodoc]] schedulers.scheduling_ddpm.DDPMSchedulerOutput
|
tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/deis.md
ADDED
|
@@ -0,0 +1,34 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# DEISMultistepScheduler
|
| 14 |
+
|
| 15 |
+
Diffusion Exponential Integrator Sampler (DEIS) is proposed in [Fast Sampling of Diffusion Models with Exponential Integrator](https://huggingface.co/papers/2204.13902) by Qinsheng Zhang and Yongxin Chen. `DEISMultistepScheduler` is a fast high order solver for diffusion ordinary differential equations (ODEs).
|
| 16 |
+
|
| 17 |
+
This implementation modifies the polynomial fitting formula in log-rho space instead of the original linear `t` space in the DEIS paper. The modification enjoys closed-form coefficients for exponential multistep update instead of replying on the numerical solver.
|
| 18 |
+
|
| 19 |
+
The abstract from the paper is:
|
| 20 |
+
|
| 21 |
+
*The past few years have witnessed the great success of Diffusion models~(DMs) in generating high-fidelity samples in generative modeling tasks. A major limitation of the DM is its notoriously slow sampling procedure which normally requires hundreds to thousands of time discretization steps of the learned diffusion process to reach the desired accuracy. Our goal is to develop a fast sampling method for DMs with a much less number of steps while retaining high sample quality. To this end, we systematically analyze the sampling procedure in DMs and identify key factors that affect the sample quality, among which the method of discretization is most crucial. By carefully examining the learned diffusion process, we propose Diffusion Exponential Integrator Sampler~(DEIS). It is based on the Exponential Integrator designed for discretizing ordinary differential equations (ODEs) and leverages a semilinear structure of the learned diffusion process to reduce the discretization error. The proposed method can be applied to any DMs and can generate high-fidelity samples in as few as 10 steps. In our experiments, it takes about 3 minutes on one A6000 GPU to generate 50k images from CIFAR10. Moreover, by directly using pre-trained DMs, we achieve the state-of-art sampling performance when the number of score function evaluation~(NFE) is limited, e.g., 4.17 FID with 10 NFEs, 3.37 FID, and 9.74 IS with only 15 NFEs on CIFAR10. Code is available at [this https URL](https://github.com/qsh-zh/deis).*
|
| 22 |
+
|
| 23 |
+
## Tips
|
| 24 |
+
|
| 25 |
+
It is recommended to set `solver_order` to 2 or 3, while `solver_order=1` is equivalent to [`DDIMScheduler`].
|
| 26 |
+
|
| 27 |
+
Dynamic thresholding from [Imagen](https://huggingface.co/papers/2205.11487) is supported, and for pixel-space
|
| 28 |
+
diffusion models, you can set `thresholding=True` to use the dynamic thresholding.
|
| 29 |
+
|
| 30 |
+
## DEISMultistepScheduler
|
| 31 |
+
[[autodoc]] DEISMultistepScheduler
|
| 32 |
+
|
| 33 |
+
## SchedulerOutput
|
| 34 |
+
[[autodoc]] schedulers.scheduling_utils.SchedulerOutput
|
tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/dpm_discrete.md
ADDED
|
@@ -0,0 +1,23 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# KDPM2DiscreteScheduler
|
| 14 |
+
|
| 15 |
+
The `KDPM2DiscreteScheduler` is inspired by the [Elucidating the Design Space of Diffusion-Based Generative Models](https://huggingface.co/papers/2206.00364) paper, and the scheduler is ported from and created by [Katherine Crowson](https://github.com/crowsonkb/).
|
| 16 |
+
|
| 17 |
+
The original codebase can be found at [crowsonkb/k-diffusion](https://github.com/crowsonkb/k-diffusion).
|
| 18 |
+
|
| 19 |
+
## KDPM2DiscreteScheduler
|
| 20 |
+
[[autodoc]] KDPM2DiscreteScheduler
|
| 21 |
+
|
| 22 |
+
## SchedulerOutput
|
| 23 |
+
[[autodoc]] schedulers.scheduling_utils.SchedulerOutput
|
tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/dpm_discrete_ancestral.md
ADDED
|
@@ -0,0 +1,23 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# KDPM2AncestralDiscreteScheduler
|
| 14 |
+
|
| 15 |
+
The `KDPM2DiscreteScheduler` with ancestral sampling is inspired by the [Elucidating the Design Space of Diffusion-Based Generative Models](https://huggingface.co/papers/2206.00364) paper, and the scheduler is ported from and created by [Katherine Crowson](https://github.com/crowsonkb/).
|
| 16 |
+
|
| 17 |
+
The original codebase can be found at [crowsonkb/k-diffusion](https://github.com/crowsonkb/k-diffusion).
|
| 18 |
+
|
| 19 |
+
## KDPM2AncestralDiscreteScheduler
|
| 20 |
+
[[autodoc]] KDPM2AncestralDiscreteScheduler
|
| 21 |
+
|
| 22 |
+
## SchedulerOutput
|
| 23 |
+
[[autodoc]] schedulers.scheduling_utils.SchedulerOutput
|
tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/dpm_sde.md
ADDED
|
@@ -0,0 +1,21 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# DPMSolverSDEScheduler
|
| 14 |
+
|
| 15 |
+
The `DPMSolverSDEScheduler` is inspired by the stochastic sampler from the [Elucidating the Design Space of Diffusion-Based Generative Models](https://huggingface.co/papers/2206.00364) paper, and the scheduler is ported from and created by [Katherine Crowson](https://github.com/crowsonkb/).
|
| 16 |
+
|
| 17 |
+
## DPMSolverSDEScheduler
|
| 18 |
+
[[autodoc]] DPMSolverSDEScheduler
|
| 19 |
+
|
| 20 |
+
## SchedulerOutput
|
| 21 |
+
[[autodoc]] schedulers.scheduling_utils.SchedulerOutput
|
tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/edm_euler.md
ADDED
|
@@ -0,0 +1,22 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# EDMEulerScheduler
|
| 14 |
+
|
| 15 |
+
The Karras formulation of the Euler scheduler (Algorithm 2) from the [Elucidating the Design Space of Diffusion-Based Generative Models](https://huggingface.co/papers/2206.00364) paper by Karras et al. This is a fast scheduler which can often generate good outputs in 20-30 steps. The scheduler is based on the original [k-diffusion](https://github.com/crowsonkb/k-diffusion/blob/481677d114f6ea445aa009cf5bd7a9cdee909e47/k_diffusion/sampling.py#L51) implementation by [Katherine Crowson](https://github.com/crowsonkb/).
|
| 16 |
+
|
| 17 |
+
|
| 18 |
+
## EDMEulerScheduler
|
| 19 |
+
[[autodoc]] EDMEulerScheduler
|
| 20 |
+
|
| 21 |
+
## EDMEulerSchedulerOutput
|
| 22 |
+
[[autodoc]] schedulers.scheduling_edm_euler.EDMEulerSchedulerOutput
|
tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/edm_multistep_dpm_solver.md
ADDED
|
@@ -0,0 +1,24 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# EDMDPMSolverMultistepScheduler
|
| 14 |
+
|
| 15 |
+
`EDMDPMSolverMultistepScheduler` is a [Karras formulation](https://huggingface.co/papers/2206.00364) of `DPMSolverMultistepScheduler`, a multistep scheduler from [DPM-Solver: A Fast ODE Solver for Diffusion Probabilistic Model Sampling in Around 10 Steps](https://huggingface.co/papers/2206.00927) and [DPM-Solver++: Fast Solver for Guided Sampling of Diffusion Probabilistic Models](https://huggingface.co/papers/2211.01095) by Cheng Lu, Yuhao Zhou, Fan Bao, Jianfei Chen, Chongxuan Li, and Jun Zhu.
|
| 16 |
+
|
| 17 |
+
DPMSolver (and the improved version DPMSolver++) is a fast dedicated high-order solver for diffusion ODEs with convergence order guarantee. Empirically, DPMSolver sampling with only 20 steps can generate high-quality
|
| 18 |
+
samples, and it can generate quite good samples even in 10 steps.
|
| 19 |
+
|
| 20 |
+
## EDMDPMSolverMultistepScheduler
|
| 21 |
+
[[autodoc]] EDMDPMSolverMultistepScheduler
|
| 22 |
+
|
| 23 |
+
## SchedulerOutput
|
| 24 |
+
[[autodoc]] schedulers.scheduling_utils.SchedulerOutput
|
tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/euler.md
ADDED
|
@@ -0,0 +1,22 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# EulerDiscreteScheduler
|
| 14 |
+
|
| 15 |
+
The Euler scheduler (Algorithm 2) is from the [Elucidating the Design Space of Diffusion-Based Generative Models](https://huggingface.co/papers/2206.00364) paper by Karras et al. This is a fast scheduler which can often generate good outputs in 20-30 steps. The scheduler is based on the original [k-diffusion](https://github.com/crowsonkb/k-diffusion/blob/481677d114f6ea445aa009cf5bd7a9cdee909e47/k_diffusion/sampling.py#L51) implementation by [Katherine Crowson](https://github.com/crowsonkb/).
|
| 16 |
+
|
| 17 |
+
|
| 18 |
+
## EulerDiscreteScheduler
|
| 19 |
+
[[autodoc]] EulerDiscreteScheduler
|
| 20 |
+
|
| 21 |
+
## EulerDiscreteSchedulerOutput
|
| 22 |
+
[[autodoc]] schedulers.scheduling_euler_discrete.EulerDiscreteSchedulerOutput
|
tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/euler_ancestral.md
ADDED
|
@@ -0,0 +1,21 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# EulerAncestralDiscreteScheduler
|
| 14 |
+
|
| 15 |
+
A scheduler that uses ancestral sampling with Euler method steps. This is a fast scheduler which can often generate good outputs in 20-30 steps. The scheduler is based on the original [k-diffusion](https://github.com/crowsonkb/k-diffusion/blob/481677d114f6ea445aa009cf5bd7a9cdee909e47/k_diffusion/sampling.py#L72) implementation by [Katherine Crowson](https://github.com/crowsonkb/).
|
| 16 |
+
|
| 17 |
+
## EulerAncestralDiscreteScheduler
|
| 18 |
+
[[autodoc]] EulerAncestralDiscreteScheduler
|
| 19 |
+
|
| 20 |
+
## EulerAncestralDiscreteSchedulerOutput
|
| 21 |
+
[[autodoc]] schedulers.scheduling_euler_ancestral_discrete.EulerAncestralDiscreteSchedulerOutput
|
tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/flow_match_euler_discrete.md
ADDED
|
@@ -0,0 +1,18 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# FlowMatchEulerDiscreteScheduler
|
| 14 |
+
|
| 15 |
+
`FlowMatchEulerDiscreteScheduler` is based on the flow-matching sampling introduced in [Stable Diffusion 3](https://huggingface.co/papers/2403.03206).
|
| 16 |
+
|
| 17 |
+
## FlowMatchEulerDiscreteScheduler
|
| 18 |
+
[[autodoc]] FlowMatchEulerDiscreteScheduler
|
tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/flow_match_heun_discrete.md
ADDED
|
@@ -0,0 +1,18 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# FlowMatchHeunDiscreteScheduler
|
| 14 |
+
|
| 15 |
+
`FlowMatchHeunDiscreteScheduler` is based on the flow-matching sampling introduced in [EDM](https://huggingface.co/papers/2403.03206).
|
| 16 |
+
|
| 17 |
+
## FlowMatchHeunDiscreteScheduler
|
| 18 |
+
[[autodoc]] FlowMatchHeunDiscreteScheduler
|
tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/heun.md
ADDED
|
@@ -0,0 +1,21 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# HeunDiscreteScheduler
|
| 14 |
+
|
| 15 |
+
The Heun scheduler (Algorithm 1) is from the [Elucidating the Design Space of Diffusion-Based Generative Models](https://huggingface.co/papers/2206.00364) paper by Karras et al. The scheduler is ported from the [k-diffusion](https://github.com/crowsonkb/k-diffusion) library and created by [Katherine Crowson](https://github.com/crowsonkb/).
|
| 16 |
+
|
| 17 |
+
## HeunDiscreteScheduler
|
| 18 |
+
[[autodoc]] HeunDiscreteScheduler
|
| 19 |
+
|
| 20 |
+
## SchedulerOutput
|
| 21 |
+
[[autodoc]] schedulers.scheduling_utils.SchedulerOutput
|
tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/ipndm.md
ADDED
|
@@ -0,0 +1,21 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# IPNDMScheduler
|
| 14 |
+
|
| 15 |
+
`IPNDMScheduler` is a fourth-order Improved Pseudo Linear Multistep scheduler. The original implementation can be found at [crowsonkb/v-diffusion-pytorch](https://github.com/crowsonkb/v-diffusion-pytorch/blob/987f8985e38208345c1959b0ea767a625831cc9b/diffusion/sampling.py#L296).
|
| 16 |
+
|
| 17 |
+
## IPNDMScheduler
|
| 18 |
+
[[autodoc]] IPNDMScheduler
|
| 19 |
+
|
| 20 |
+
## SchedulerOutput
|
| 21 |
+
[[autodoc]] schedulers.scheduling_utils.SchedulerOutput
|
tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/lcm.md
ADDED
|
@@ -0,0 +1,21 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Latent Consistency Model Multistep Scheduler
|
| 14 |
+
|
| 15 |
+
## Overview
|
| 16 |
+
|
| 17 |
+
Multistep and onestep scheduler (Algorithm 3) introduced alongside latent consistency models in the paper [Latent Consistency Models: Synthesizing High-Resolution Images with Few-Step Inference](https://huggingface.co/papers/2310.04378) by Simian Luo, Yiqin Tan, Longbo Huang, Jian Li, and Hang Zhao.
|
| 18 |
+
This scheduler should be able to generate good samples from [`LatentConsistencyModelPipeline`] in 1-8 steps.
|
| 19 |
+
|
| 20 |
+
## LCMScheduler
|
| 21 |
+
[[autodoc]] LCMScheduler
|
tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/lms_discrete.md
ADDED
|
@@ -0,0 +1,21 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# LMSDiscreteScheduler
|
| 14 |
+
|
| 15 |
+
`LMSDiscreteScheduler` is a linear multistep scheduler for discrete beta schedules. The scheduler is ported from and created by [Katherine Crowson](https://github.com/crowsonkb/), and the original implementation can be found at [crowsonkb/k-diffusion](https://github.com/crowsonkb/k-diffusion/blob/481677d114f6ea445aa009cf5bd7a9cdee909e47/k_diffusion/sampling.py#L181).
|
| 16 |
+
|
| 17 |
+
## LMSDiscreteScheduler
|
| 18 |
+
[[autodoc]] LMSDiscreteScheduler
|
| 19 |
+
|
| 20 |
+
## LMSDiscreteSchedulerOutput
|
| 21 |
+
[[autodoc]] schedulers.scheduling_lms_discrete.LMSDiscreteSchedulerOutput
|
tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/multistep_dpm_solver.md
ADDED
|
@@ -0,0 +1,35 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# DPMSolverMultistepScheduler
|
| 14 |
+
|
| 15 |
+
`DPMSolverMultistepScheduler` is a multistep scheduler from [DPM-Solver: A Fast ODE Solver for Diffusion Probabilistic Model Sampling in Around 10 Steps](https://huggingface.co/papers/2206.00927) and [DPM-Solver++: Fast Solver for Guided Sampling of Diffusion Probabilistic Models](https://huggingface.co/papers/2211.01095) by Cheng Lu, Yuhao Zhou, Fan Bao, Jianfei Chen, Chongxuan Li, and Jun Zhu.
|
| 16 |
+
|
| 17 |
+
DPMSolver (and the improved version DPMSolver++) is a fast dedicated high-order solver for diffusion ODEs with convergence order guarantee. Empirically, DPMSolver sampling with only 20 steps can generate high-quality
|
| 18 |
+
samples, and it can generate quite good samples even in 10 steps.
|
| 19 |
+
|
| 20 |
+
## Tips
|
| 21 |
+
|
| 22 |
+
It is recommended to set `solver_order` to 2 for guide sampling, and `solver_order=3` for unconditional sampling.
|
| 23 |
+
|
| 24 |
+
Dynamic thresholding from [Imagen](https://huggingface.co/papers/2205.11487) is supported, and for pixel-space
|
| 25 |
+
diffusion models, you can set both `algorithm_type="dpmsolver++"` and `thresholding=True` to use the dynamic
|
| 26 |
+
thresholding. This thresholding method is unsuitable for latent-space diffusion models such as
|
| 27 |
+
Stable Diffusion.
|
| 28 |
+
|
| 29 |
+
The SDE variant of DPMSolver and DPM-Solver++ is also supported, but only for the first and second-order solvers. This is a fast SDE solver for the reverse diffusion SDE. It is recommended to use the second-order `sde-dpmsolver++`.
|
| 30 |
+
|
| 31 |
+
## DPMSolverMultistepScheduler
|
| 32 |
+
[[autodoc]] DPMSolverMultistepScheduler
|
| 33 |
+
|
| 34 |
+
## SchedulerOutput
|
| 35 |
+
[[autodoc]] schedulers.scheduling_utils.SchedulerOutput
|
tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/multistep_dpm_solver_cogvideox.md
ADDED
|
@@ -0,0 +1,19 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# CogVideoXDPMScheduler
|
| 14 |
+
|
| 15 |
+
`CogVideoXDPMScheduler` is based on [DPM-Solver: A Fast ODE Solver for Diffusion Probabilistic Model Sampling in Around 10 Steps](https://huggingface.co/papers/2206.00927) and [DPM-Solver++: Fast Solver for Guided Sampling of Diffusion Probabilistic Models](https://huggingface.co/papers/2211.01095), specifically for CogVideoX models.
|
| 16 |
+
|
| 17 |
+
## CogVideoXDPMScheduler
|
| 18 |
+
|
| 19 |
+
[[autodoc]] CogVideoXDPMScheduler
|
tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/multistep_dpm_solver_inverse.md
ADDED
|
@@ -0,0 +1,30 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# DPMSolverMultistepInverse
|
| 14 |
+
|
| 15 |
+
`DPMSolverMultistepInverse` is the inverted scheduler from [DPM-Solver: A Fast ODE Solver for Diffusion Probabilistic Model Sampling in Around 10 Steps](https://huggingface.co/papers/2206.00927) and [DPM-Solver++: Fast Solver for Guided Sampling of Diffusion Probabilistic Models](https://huggingface.co/papers/2211.01095) by Cheng Lu, Yuhao Zhou, Fan Bao, Jianfei Chen, Chongxuan Li, and Jun Zhu.
|
| 16 |
+
|
| 17 |
+
The implementation is mostly based on the DDIM inversion definition of [Null-text Inversion for Editing Real Images using Guided Diffusion Models](https://huggingface.co/papers/2211.09794) and notebook implementation of the [`DiffEdit`] latent inversion from [Xiang-cd/DiffEdit-stable-diffusion](https://github.com/Xiang-cd/DiffEdit-stable-diffusion/blob/main/diffedit.ipynb).
|
| 18 |
+
|
| 19 |
+
## Tips
|
| 20 |
+
|
| 21 |
+
Dynamic thresholding from [Imagen](https://huggingface.co/papers/2205.11487) is supported, and for pixel-space
|
| 22 |
+
diffusion models, you can set both `algorithm_type="dpmsolver++"` and `thresholding=True` to use the dynamic
|
| 23 |
+
thresholding. This thresholding method is unsuitable for latent-space diffusion models such as
|
| 24 |
+
Stable Diffusion.
|
| 25 |
+
|
| 26 |
+
## DPMSolverMultistepInverseScheduler
|
| 27 |
+
[[autodoc]] DPMSolverMultistepInverseScheduler
|
| 28 |
+
|
| 29 |
+
## SchedulerOutput
|
| 30 |
+
[[autodoc]] schedulers.scheduling_utils.SchedulerOutput
|
tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/overview.md
ADDED
|
@@ -0,0 +1,73 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Schedulers
|
| 14 |
+
|
| 15 |
+
🤗 Diffusers provides many scheduler functions for the diffusion process. A scheduler takes a model's output (the sample which the diffusion process is iterating on) and a timestep to return a denoised sample. The timestep is important because it dictates where in the diffusion process the step is; data is generated by iterating forward *n* timesteps and inference occurs by propagating backward through the timesteps. Based on the timestep, a scheduler may be *discrete* in which case the timestep is an `int` or *continuous* in which case the timestep is a `float`.
|
| 16 |
+
|
| 17 |
+
Depending on the context, a scheduler defines how to iteratively add noise to an image or how to update a sample based on a model's output:
|
| 18 |
+
|
| 19 |
+
- during *training*, a scheduler adds noise (there are different algorithms for how to add noise) to a sample to train a diffusion model
|
| 20 |
+
- during *inference*, a scheduler defines how to update a sample based on a pretrained model's output
|
| 21 |
+
|
| 22 |
+
Many schedulers are implemented from the [k-diffusion](https://github.com/crowsonkb/k-diffusion) library by [Katherine Crowson](https://github.com/crowsonkb/), and they're also widely used in A1111. To help you map the schedulers from k-diffusion and A1111 to the schedulers in 🤗 Diffusers, take a look at the table below:
|
| 23 |
+
|
| 24 |
+
| A1111/k-diffusion | 🤗 Diffusers | Usage |
|
| 25 |
+
|---------------------|-------------------------------------|---------------------------------------------------------------------------------------------------------------|
|
| 26 |
+
| DPM++ 2M | [`DPMSolverMultistepScheduler`] | |
|
| 27 |
+
| DPM++ 2M Karras | [`DPMSolverMultistepScheduler`] | init with `use_karras_sigmas=True` |
|
| 28 |
+
| DPM++ 2M SDE | [`DPMSolverMultistepScheduler`] | init with `algorithm_type="sde-dpmsolver++"` |
|
| 29 |
+
| DPM++ 2M SDE Karras | [`DPMSolverMultistepScheduler`] | init with `use_karras_sigmas=True` and `algorithm_type="sde-dpmsolver++"` |
|
| 30 |
+
| DPM++ 2S a | N/A | very similar to `DPMSolverSinglestepScheduler` |
|
| 31 |
+
| DPM++ 2S a Karras | N/A | very similar to `DPMSolverSinglestepScheduler(use_karras_sigmas=True, ...)` |
|
| 32 |
+
| DPM++ SDE | [`DPMSolverSinglestepScheduler`] | |
|
| 33 |
+
| DPM++ SDE Karras | [`DPMSolverSinglestepScheduler`] | init with `use_karras_sigmas=True` |
|
| 34 |
+
| DPM2 | [`KDPM2DiscreteScheduler`] | |
|
| 35 |
+
| DPM2 Karras | [`KDPM2DiscreteScheduler`] | init with `use_karras_sigmas=True` |
|
| 36 |
+
| DPM2 a | [`KDPM2AncestralDiscreteScheduler`] | |
|
| 37 |
+
| DPM2 a Karras | [`KDPM2AncestralDiscreteScheduler`] | init with `use_karras_sigmas=True` |
|
| 38 |
+
| DPM adaptive | N/A | |
|
| 39 |
+
| DPM fast | N/A | |
|
| 40 |
+
| Euler | [`EulerDiscreteScheduler`] | |
|
| 41 |
+
| Euler a | [`EulerAncestralDiscreteScheduler`] | |
|
| 42 |
+
| Heun | [`HeunDiscreteScheduler`] | |
|
| 43 |
+
| LMS | [`LMSDiscreteScheduler`] | |
|
| 44 |
+
| LMS Karras | [`LMSDiscreteScheduler`] | init with `use_karras_sigmas=True` |
|
| 45 |
+
| N/A | [`DEISMultistepScheduler`] | |
|
| 46 |
+
| N/A | [`UniPCMultistepScheduler`] | |
|
| 47 |
+
|
| 48 |
+
## Noise schedules and schedule types
|
| 49 |
+
| A1111/k-diffusion | 🤗 Diffusers |
|
| 50 |
+
|--------------------------|----------------------------------------------------------------------------|
|
| 51 |
+
| Karras | init with `use_karras_sigmas=True` |
|
| 52 |
+
| sgm_uniform | init with `timestep_spacing="trailing"` |
|
| 53 |
+
| simple | init with `timestep_spacing="trailing"` |
|
| 54 |
+
| exponential | init with `timestep_spacing="linspace"`, `use_exponential_sigmas=True` |
|
| 55 |
+
| beta | init with `timestep_spacing="linspace"`, `use_beta_sigmas=True` |
|
| 56 |
+
|
| 57 |
+
All schedulers are built from the base [`SchedulerMixin`] class which implements low level utilities shared by all schedulers.
|
| 58 |
+
|
| 59 |
+
## SchedulerMixin
|
| 60 |
+
[[autodoc]] SchedulerMixin
|
| 61 |
+
|
| 62 |
+
## SchedulerOutput
|
| 63 |
+
[[autodoc]] schedulers.scheduling_utils.SchedulerOutput
|
| 64 |
+
|
| 65 |
+
## KarrasDiffusionSchedulers
|
| 66 |
+
|
| 67 |
+
[`KarrasDiffusionSchedulers`] are a broad generalization of schedulers in 🤗 Diffusers. The schedulers in this class are distinguished at a high level by their noise sampling strategy, the type of network and scaling, the training strategy, and how the loss is weighed.
|
| 68 |
+
|
| 69 |
+
The different schedulers in this class, depending on the ordinary differential equations (ODE) solver type, fall into the above taxonomy and provide a good abstraction for the design of the main schedulers implemented in 🤗 Diffusers. The schedulers in this class are given [here](https://github.com/huggingface/diffusers/blob/a69754bb879ed55b9b6dc9dd0b3cf4fa4124c765/src/diffusers/schedulers/scheduling_utils.py#L32).
|
| 70 |
+
|
| 71 |
+
## PushToHubMixin
|
| 72 |
+
|
| 73 |
+
[[autodoc]] utils.PushToHubMixin
|
tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/pndm.md
ADDED
|
@@ -0,0 +1,21 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# PNDMScheduler
|
| 14 |
+
|
| 15 |
+
`PNDMScheduler`, or pseudo numerical methods for diffusion models, uses more advanced ODE integration techniques like the Runge-Kutta and linear multi-step method. The original implementation can be found at [crowsonkb/k-diffusion](https://github.com/crowsonkb/k-diffusion/blob/481677d114f6ea445aa009cf5bd7a9cdee909e47/k_diffusion/sampling.py#L181).
|
| 16 |
+
|
| 17 |
+
## PNDMScheduler
|
| 18 |
+
[[autodoc]] PNDMScheduler
|
| 19 |
+
|
| 20 |
+
## SchedulerOutput
|
| 21 |
+
[[autodoc]] schedulers.scheduling_utils.SchedulerOutput
|
tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/repaint.md
ADDED
|
@@ -0,0 +1,27 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# RePaintScheduler
|
| 14 |
+
|
| 15 |
+
`RePaintScheduler` is a DDPM-based inpainting scheduler for unsupervised inpainting with extreme masks. It is designed to be used with the [`RePaintPipeline`], and it is based on the paper [RePaint: Inpainting using Denoising Diffusion Probabilistic Models](https://huggingface.co/papers/2201.09865) by Andreas Lugmayr et al.
|
| 16 |
+
|
| 17 |
+
The abstract from the paper is:
|
| 18 |
+
|
| 19 |
+
*Free-form inpainting is the task of adding new content to an image in the regions specified by an arbitrary binary mask. Most existing approaches train for a certain distribution of masks, which limits their generalization capabilities to unseen mask types. Furthermore, training with pixel-wise and perceptual losses often leads to simple textural extensions towards the missing areas instead of semantically meaningful generation. In this work, we propose RePaint: A Denoising Diffusion Probabilistic Model (DDPM) based inpainting approach that is applicable to even extreme masks. We employ a pretrained unconditional DDPM as the generative prior. To condition the generation process, we only alter the reverse diffusion iterations by sampling the unmasked regions using the given image information. Since this technique does not modify or condition the original DDPM network itself, the model produces high-quality and diverse output images for any inpainting form. We validate our method for both faces and general-purpose image inpainting using standard and extreme masks. RePaint outperforms state-of-the-art Autoregressive, and GAN approaches for at least five out of six mask distributions. GitHub Repository: [this http URL](http://git.io/RePaint).*
|
| 20 |
+
|
| 21 |
+
The original implementation can be found at [andreas128/RePaint](https://github.com/andreas128/).
|
| 22 |
+
|
| 23 |
+
## RePaintScheduler
|
| 24 |
+
[[autodoc]] RePaintScheduler
|
| 25 |
+
|
| 26 |
+
## RePaintSchedulerOutput
|
| 27 |
+
[[autodoc]] schedulers.scheduling_repaint.RePaintSchedulerOutput
|
tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/score_sde_ve.md
ADDED
|
@@ -0,0 +1,25 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# ScoreSdeVeScheduler
|
| 14 |
+
|
| 15 |
+
`ScoreSdeVeScheduler` is a variance exploding stochastic differential equation (SDE) scheduler. It was introduced in the [Score-Based Generative Modeling through Stochastic Differential Equations](https://huggingface.co/papers/2011.13456) paper by Yang Song, Jascha Sohl-Dickstein, Diederik P. Kingma, Abhishek Kumar, Stefano Ermon, Ben Poole.
|
| 16 |
+
|
| 17 |
+
The abstract from the paper is:
|
| 18 |
+
|
| 19 |
+
*Creating noise from data is easy; creating data from noise is generative modeling. We present a stochastic differential equation (SDE) that smoothly transforms a complex data distribution to a known prior distribution by slowly injecting noise, and a corresponding reverse-time SDE that transforms the prior distribution back into the data distribution by slowly removing the noise. Crucially, the reverse-time SDE depends only on the time-dependent gradient field (\aka, score) of the perturbed data distribution. By leveraging advances in score-based generative modeling, we can accurately estimate these scores with neural networks, and use numerical SDE solvers to generate samples. We show that this framework encapsulates previous approaches in score-based generative modeling and diffusion probabilistic modeling, allowing for new sampling procedures and new modeling capabilities. In particular, we introduce a predictor-corrector framework to correct errors in the evolution of the discretized reverse-time SDE. We also derive an equivalent neural ODE that samples from the same distribution as the SDE, but additionally enables exact likelihood computation, and improved sampling efficiency. In addition, we provide a new way to solve inverse problems with score-based models, as demonstrated with experiments on class-conditional generation, image inpainting, and colorization. Combined with multiple architectural improvements, we achieve record-breaking performance for unconditional image generation on CIFAR-10 with an Inception score of 9.89 and FID of 2.20, a competitive likelihood of 2.99 bits/dim, and demonstrate high fidelity generation of 1024 x 1024 images for the first time from a score-based generative model.*
|
| 20 |
+
|
| 21 |
+
## ScoreSdeVeScheduler
|
| 22 |
+
[[autodoc]] ScoreSdeVeScheduler
|
| 23 |
+
|
| 24 |
+
## SdeVeOutput
|
| 25 |
+
[[autodoc]] schedulers.scheduling_sde_ve.SdeVeOutput
|
tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/score_sde_vp.md
ADDED
|
@@ -0,0 +1,25 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# ScoreSdeVpScheduler
|
| 14 |
+
|
| 15 |
+
`ScoreSdeVpScheduler` is a variance preserving stochastic differential equation (SDE) scheduler. It was introduced in the [Score-Based Generative Modeling through Stochastic Differential Equations](https://huggingface.co/papers/2011.13456) paper by Yang Song, Jascha Sohl-Dickstein, Diederik P. Kingma, Abhishek Kumar, Stefano Ermon, Ben Poole.
|
| 16 |
+
|
| 17 |
+
The abstract from the paper is:
|
| 18 |
+
|
| 19 |
+
*Creating noise from data is easy; creating data from noise is generative modeling. We present a stochastic differential equation (SDE) that smoothly transforms a complex data distribution to a known prior distribution by slowly injecting noise, and a corresponding reverse-time SDE that transforms the prior distribution back into the data distribution by slowly removing the noise. Crucially, the reverse-time SDE depends only on the time-dependent gradient field (\aka, score) of the perturbed data distribution. By leveraging advances in score-based generative modeling, we can accurately estimate these scores with neural networks, and use numerical SDE solvers to generate samples. We show that this framework encapsulates previous approaches in score-based generative modeling and diffusion probabilistic modeling, allowing for new sampling procedures and new modeling capabilities. In particular, we introduce a predictor-corrector framework to correct errors in the evolution of the discretized reverse-time SDE. We also derive an equivalent neural ODE that samples from the same distribution as the SDE, but additionally enables exact likelihood computation, and improved sampling efficiency. In addition, we provide a new way to solve inverse problems with score-based models, as demonstrated with experiments on class-conditional generation, image inpainting, and colorization. Combined with multiple architectural improvements, we achieve record-breaking performance for unconditional image generation on CIFAR-10 with an Inception score of 9.89 and FID of 2.20, a competitive likelihood of 2.99 bits/dim, and demonstrate high fidelity generation of 1024 x 1024 images for the first time from a score-based generative model.*
|
| 20 |
+
|
| 21 |
+
> [!WARNING]
|
| 22 |
+
> 🚧 This scheduler is under construction!
|
| 23 |
+
|
| 24 |
+
## ScoreSdeVpScheduler
|
| 25 |
+
[[autodoc]] schedulers.deprecated.scheduling_sde_vp.ScoreSdeVpScheduler
|
tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/singlestep_dpm_solver.md
ADDED
|
@@ -0,0 +1,35 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# DPMSolverSinglestepScheduler
|
| 14 |
+
|
| 15 |
+
`DPMSolverSinglestepScheduler` is a single step scheduler from [DPM-Solver: A Fast ODE Solver for Diffusion Probabilistic Model Sampling in Around 10 Steps](https://huggingface.co/papers/2206.00927) and [DPM-Solver++: Fast Solver for Guided Sampling of Diffusion Probabilistic Models](https://huggingface.co/papers/2211.01095) by Cheng Lu, Yuhao Zhou, Fan Bao, Jianfei Chen, Chongxuan Li, and Jun Zhu.
|
| 16 |
+
|
| 17 |
+
DPMSolver (and the improved version DPMSolver++) is a fast dedicated high-order solver for diffusion ODEs with convergence order guarantee. Empirically, DPMSolver sampling with only 20 steps can generate high-quality
|
| 18 |
+
samples, and it can generate quite good samples even in 10 steps.
|
| 19 |
+
|
| 20 |
+
The original implementation can be found at [LuChengTHU/dpm-solver](https://github.com/LuChengTHU/dpm-solver).
|
| 21 |
+
|
| 22 |
+
## Tips
|
| 23 |
+
|
| 24 |
+
It is recommended to set `solver_order` to 2 for guide sampling, and `solver_order=3` for unconditional sampling.
|
| 25 |
+
|
| 26 |
+
Dynamic thresholding from [Imagen](https://huggingface.co/papers/2205.11487) is supported, and for pixel-space
|
| 27 |
+
diffusion models, you can set both `algorithm_type="dpmsolver++"` and `thresholding=True` to use dynamic
|
| 28 |
+
thresholding. This thresholding method is unsuitable for latent-space diffusion models such as
|
| 29 |
+
Stable Diffusion.
|
| 30 |
+
|
| 31 |
+
## DPMSolverSinglestepScheduler
|
| 32 |
+
[[autodoc]] DPMSolverSinglestepScheduler
|
| 33 |
+
|
| 34 |
+
## SchedulerOutput
|
| 35 |
+
[[autodoc]] schedulers.scheduling_utils.SchedulerOutput
|
tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/stochastic_karras_ve.md
ADDED
|
@@ -0,0 +1,21 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# KarrasVeScheduler
|
| 14 |
+
|
| 15 |
+
`KarrasVeScheduler` is a stochastic sampler tailored to variance-expanding (VE) models. It is based on the [Elucidating the Design Space of Diffusion-Based Generative Models](https://huggingface.co/papers/2206.00364) and [Score-based generative modeling through stochastic differential equations](https://huggingface.co/papers/2011.13456) papers.
|
| 16 |
+
|
| 17 |
+
## KarrasVeScheduler
|
| 18 |
+
[[autodoc]] KarrasVeScheduler
|
| 19 |
+
|
| 20 |
+
## KarrasVeOutput
|
| 21 |
+
[[autodoc]] schedulers.deprecated.scheduling_karras_ve.KarrasVeOutput
|
tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/tcd.md
ADDED
|
@@ -0,0 +1,29 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# TCDScheduler
|
| 14 |
+
|
| 15 |
+
[Trajectory Consistency Distillation](https://huggingface.co/papers/2402.19159) by Jianbin Zheng, Minghui Hu, Zhongyi Fan, Chaoyue Wang, Changxing Ding, Dacheng Tao and Tat-Jen Cham introduced a Strategic Stochastic Sampling (Algorithm 4) that is capable of generating good samples in a small number of steps. Distinguishing it as an advanced iteration of the multistep scheduler (Algorithm 1) in the [Consistency Models](https://huggingface.co/papers/2303.01469), Strategic Stochastic Sampling specifically tailored for the trajectory consistency function.
|
| 16 |
+
|
| 17 |
+
The abstract from the paper is:
|
| 18 |
+
|
| 19 |
+
*Latent Consistency Model (LCM) extends the Consistency Model to the latent space and leverages the guided consistency distillation technique to achieve impressive performance in accelerating text-to-image synthesis. However, we observed that LCM struggles to generate images with both clarity and detailed intricacy. To address this limitation, we initially delve into and elucidate the underlying causes. Our investigation identifies that the primary issue stems from errors in three distinct areas. Consequently, we introduce Trajectory Consistency Distillation (TCD), which encompasses trajectory consistency function and strategic stochastic sampling. The trajectory consistency function diminishes the distillation errors by broadening the scope of the self-consistency boundary condition and endowing the TCD with the ability to accurately trace the entire trajectory of the Probability Flow ODE. Additionally, strategic stochastic sampling is specifically designed to circumvent the accumulated errors inherent in multi-step consistency sampling, which is meticulously tailored to complement the TCD model. Experiments demonstrate that TCD not only significantly enhances image quality at low NFEs but also yields more detailed results compared to the teacher model at high NFEs.*
|
| 20 |
+
|
| 21 |
+
The original codebase can be found at [jabir-zheng/TCD](https://github.com/jabir-zheng/TCD).
|
| 22 |
+
|
| 23 |
+
## TCDScheduler
|
| 24 |
+
[[autodoc]] TCDScheduler
|
| 25 |
+
|
| 26 |
+
|
| 27 |
+
## TCDSchedulerOutput
|
| 28 |
+
[[autodoc]] schedulers.scheduling_tcd.TCDSchedulerOutput
|
| 29 |
+
|
tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/unipc.md
ADDED
|
@@ -0,0 +1,35 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# UniPCMultistepScheduler
|
| 14 |
+
|
| 15 |
+
`UniPCMultistepScheduler` is a training-free framework designed for fast sampling of diffusion models. It was introduced in [UniPC: A Unified Predictor-Corrector Framework for Fast Sampling of Diffusion Models](https://huggingface.co/papers/2302.04867) by Wenliang Zhao, Lujia Bai, Yongming Rao, Jie Zhou, Jiwen Lu.
|
| 16 |
+
|
| 17 |
+
It consists of a corrector (UniC) and a predictor (UniP) that share a unified analytical form and support arbitrary orders.
|
| 18 |
+
UniPC is by design model-agnostic, supporting pixel-space/latent-space DPMs on unconditional/conditional sampling. It can also be applied to both noise prediction and data prediction models. The corrector UniC can be also applied after any off-the-shelf solvers to increase the order of accuracy.
|
| 19 |
+
|
| 20 |
+
The abstract from the paper is:
|
| 21 |
+
|
| 22 |
+
*Diffusion probabilistic models (DPMs) have demonstrated a very promising ability in high-resolution image synthesis. However, sampling from a pre-trained DPM is time-consuming due to the multiple evaluations of the denoising network, making it more and more important to accelerate the sampling of DPMs. Despite recent progress in designing fast samplers, existing methods still cannot generate satisfying images in many applications where fewer steps (e.g., <10) are favored. In this paper, we develop a unified corrector (UniC) that can be applied after any existing DPM sampler to increase the order of accuracy without extra model evaluations, and derive a unified predictor (UniP) that supports arbitrary order as a byproduct. Combining UniP and UniC, we propose a unified predictor-corrector framework called UniPC for the fast sampling of DPMs, which has a unified analytical form for any order and can significantly improve the sampling quality over previous methods, especially in extremely few steps. We evaluate our methods through extensive experiments including both unconditional and conditional sampling using pixel-space and latent-space DPMs. Our UniPC can achieve 3.87 FID on CIFAR10 (unconditional) and 7.51 FID on ImageNet 256×256 (conditional) with only 10 function evaluations. Code is available at [this https URL](https://github.com/wl-zhao/UniPC).*
|
| 23 |
+
|
| 24 |
+
## Tips
|
| 25 |
+
|
| 26 |
+
It is recommended to set `solver_order` to 2 for guide sampling, and `solver_order=3` for unconditional sampling.
|
| 27 |
+
|
| 28 |
+
Dynamic thresholding from [Imagen](https://huggingface.co/papers/2205.11487) is supported, and for pixel-space
|
| 29 |
+
diffusion models, you can set both `predict_x0=True` and `thresholding=True` to use dynamic thresholding. This thresholding method is unsuitable for latent-space diffusion models such as Stable Diffusion.
|
| 30 |
+
|
| 31 |
+
## UniPCMultistepScheduler
|
| 32 |
+
[[autodoc]] UniPCMultistepScheduler
|
| 33 |
+
|
| 34 |
+
## SchedulerOutput
|
| 35 |
+
[[autodoc]] schedulers.scheduling_utils.SchedulerOutput
|
tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/schedulers/vq_diffusion.md
ADDED
|
@@ -0,0 +1,25 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# VQDiffusionScheduler
|
| 14 |
+
|
| 15 |
+
`VQDiffusionScheduler` converts the transformer model's output into a sample for the unnoised image at the previous diffusion timestep. It was introduced in [Vector Quantized Diffusion Model for Text-to-Image Synthesis](https://huggingface.co/papers/2111.14822) by Shuyang Gu, Dong Chen, Jianmin Bao, Fang Wen, Bo Zhang, Dongdong Chen, Lu Yuan, Baining Guo.
|
| 16 |
+
|
| 17 |
+
The abstract from the paper is:
|
| 18 |
+
|
| 19 |
+
*We present the vector quantized diffusion (VQ-Diffusion) model for text-to-image generation. This method is based on a vector quantized variational autoencoder (VQ-VAE) whose latent space is modeled by a conditional variant of the recently developed Denoising Diffusion Probabilistic Model (DDPM). We find that this latent-space method is well-suited for text-to-image generation tasks because it not only eliminates the unidirectional bias with existing methods but also allows us to incorporate a mask-and-replace diffusion strategy to avoid the accumulation of errors, which is a serious problem with existing methods. Our experiments show that the VQ-Diffusion produces significantly better text-to-image generation results when compared with conventional autoregressive (AR) models with similar numbers of parameters. Compared with previous GAN-based text-to-image methods, our VQ-Diffusion can handle more complex scenes and improve the synthesized image quality by a large margin. Finally, we show that the image generation computation in our method can be made highly efficient by reparameterization. With traditional AR methods, the text-to-image generation time increases linearly with the output image resolution and hence is quite time consuming even for normal size images. The VQ-Diffusion allows us to achieve a better trade-off between quality and speed. Our experiments indicate that the VQ-Diffusion model with the reparameterization is fifteen times faster than traditional AR methods while achieving a better image quality.*
|
| 20 |
+
|
| 21 |
+
## VQDiffusionScheduler
|
| 22 |
+
[[autodoc]] VQDiffusionScheduler
|
| 23 |
+
|
| 24 |
+
## VQDiffusionSchedulerOutput
|
| 25 |
+
[[autodoc]] schedulers.scheduling_vq_diffusion.VQDiffusionSchedulerOutput
|
tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/utilities.md
ADDED
|
@@ -0,0 +1,55 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Utilities
|
| 14 |
+
|
| 15 |
+
Utility and helper functions for working with 🤗 Diffusers.
|
| 16 |
+
|
| 17 |
+
## numpy_to_pil
|
| 18 |
+
|
| 19 |
+
[[autodoc]] utils.numpy_to_pil
|
| 20 |
+
|
| 21 |
+
## pt_to_pil
|
| 22 |
+
|
| 23 |
+
[[autodoc]] utils.pt_to_pil
|
| 24 |
+
|
| 25 |
+
## load_image
|
| 26 |
+
|
| 27 |
+
[[autodoc]] utils.load_image
|
| 28 |
+
|
| 29 |
+
## load_video
|
| 30 |
+
|
| 31 |
+
[[autodoc]] utils.load_video
|
| 32 |
+
|
| 33 |
+
## export_to_gif
|
| 34 |
+
|
| 35 |
+
[[autodoc]] utils.export_to_gif
|
| 36 |
+
|
| 37 |
+
## export_to_video
|
| 38 |
+
|
| 39 |
+
[[autodoc]] utils.export_to_video
|
| 40 |
+
|
| 41 |
+
## make_image_grid
|
| 42 |
+
|
| 43 |
+
[[autodoc]] utils.make_image_grid
|
| 44 |
+
|
| 45 |
+
## randn_tensor
|
| 46 |
+
|
| 47 |
+
[[autodoc]] utils.torch_utils.randn_tensor
|
| 48 |
+
|
| 49 |
+
## apply_layerwise_casting
|
| 50 |
+
|
| 51 |
+
[[autodoc]] hooks.layerwise_casting.apply_layerwise_casting
|
| 52 |
+
|
| 53 |
+
## apply_group_offloading
|
| 54 |
+
|
| 55 |
+
[[autodoc]] hooks.group_offloading.apply_group_offloading
|
tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/api/video_processor.md
ADDED
|
@@ -0,0 +1,21 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Video Processor
|
| 14 |
+
|
| 15 |
+
The [`VideoProcessor`] provides a unified API for video pipelines to prepare inputs for VAE encoding and post-processing outputs once they're decoded. The class inherits [`VaeImageProcessor`] so it includes transformations such as resizing, normalization, and conversion between PIL Image, PyTorch, and NumPy arrays.
|
| 16 |
+
|
| 17 |
+
## VideoProcessor
|
| 18 |
+
|
| 19 |
+
[[autodoc]] video_processor.VideoProcessor.preprocess_video
|
| 20 |
+
|
| 21 |
+
[[autodoc]] video_processor.VideoProcessor.postprocess_video
|
tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/community_projects.md
ADDED
|
@@ -0,0 +1,90 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Community Projects
|
| 14 |
+
|
| 15 |
+
Welcome to Community Projects. This space is dedicated to showcasing the incredible work and innovative applications created by our vibrant community using the `diffusers` library.
|
| 16 |
+
|
| 17 |
+
This section aims to:
|
| 18 |
+
|
| 19 |
+
- Highlight diverse and inspiring projects built with `diffusers`
|
| 20 |
+
- Foster knowledge sharing within our community
|
| 21 |
+
- Provide real-world examples of how `diffusers` can be leveraged
|
| 22 |
+
|
| 23 |
+
Happy exploring, and thank you for being part of the Diffusers community!
|
| 24 |
+
|
| 25 |
+
<table>
|
| 26 |
+
<tr>
|
| 27 |
+
<th>Project Name</th>
|
| 28 |
+
<th>Description</th>
|
| 29 |
+
</tr>
|
| 30 |
+
<tr style="border-top: 2px solid black">
|
| 31 |
+
<td><a href="https://github.com/carson-katri/dream-textures"> dream-textures </a></td>
|
| 32 |
+
<td>Stable Diffusion built-in to Blender</td>
|
| 33 |
+
</tr>
|
| 34 |
+
<tr style="border-top: 2px solid black">
|
| 35 |
+
<td><a href="https://github.com/megvii-research/HiDiffusion"> HiDiffusion </a></td>
|
| 36 |
+
<td>Increases the resolution and speed of your diffusion model by only adding a single line of code</td>
|
| 37 |
+
</tr>
|
| 38 |
+
<tr style="border-top: 2px solid black">
|
| 39 |
+
<td><a href="https://github.com/lllyasviel/IC-Light"> IC-Light </a></td>
|
| 40 |
+
<td>IC-Light is a project to manipulate the illumination of images</td>
|
| 41 |
+
</tr>
|
| 42 |
+
<tr style="border-top: 2px solid black">
|
| 43 |
+
<td><a href="https://github.com/InstantID/InstantID"> InstantID </a></td>
|
| 44 |
+
<td>InstantID : Zero-shot Identity-Preserving Generation in Seconds</td>
|
| 45 |
+
</tr>
|
| 46 |
+
<tr style="border-top: 2px solid black">
|
| 47 |
+
<td><a href="https://github.com/Sanster/IOPaint"> IOPaint </a></td>
|
| 48 |
+
<td>Image inpainting tool powered by SOTA AI Model. Remove any unwanted object, defect, people from your pictures or erase and replace(powered by stable diffusion) any thing on your pictures.</td>
|
| 49 |
+
</tr>
|
| 50 |
+
<tr style="border-top: 2px solid black">
|
| 51 |
+
<td><a href="https://github.com/bmaltais/kohya_ss"> Kohya </a></td>
|
| 52 |
+
<td>Gradio GUI for Kohya's Stable Diffusion trainers</td>
|
| 53 |
+
</tr>
|
| 54 |
+
<tr style="border-top: 2px solid black">
|
| 55 |
+
<td><a href="https://github.com/magic-research/magic-animate"> MagicAnimate </a></td>
|
| 56 |
+
<td>MagicAnimate: Temporally Consistent Human Image Animation using Diffusion Model</td>
|
| 57 |
+
</tr>
|
| 58 |
+
<tr style="border-top: 2px solid black">
|
| 59 |
+
<td><a href="https://github.com/levihsu/OOTDiffusion"> OOTDiffusion </a></td>
|
| 60 |
+
<td>Outfitting Fusion based Latent Diffusion for Controllable Virtual Try-on</td>
|
| 61 |
+
</tr>
|
| 62 |
+
<tr style="border-top: 2px solid black">
|
| 63 |
+
<td><a href="https://github.com/vladmandic/automatic"> SD.Next </a></td>
|
| 64 |
+
<td>SD.Next: Advanced Implementation of Stable Diffusion and other Diffusion-based generative image models</td>
|
| 65 |
+
</tr>
|
| 66 |
+
<tr style="border-top: 2px solid black">
|
| 67 |
+
<td><a href="https://github.com/ashawkey/stable-dreamfusion"> stable-dreamfusion </a></td>
|
| 68 |
+
<td>Text-to-3D & Image-to-3D & Mesh Exportation with NeRF + Diffusion</td>
|
| 69 |
+
</tr>
|
| 70 |
+
<tr style="border-top: 2px solid black">
|
| 71 |
+
<td><a href="https://github.com/HVision-NKU/StoryDiffusion"> StoryDiffusion </a></td>
|
| 72 |
+
<td>StoryDiffusion can create a magic story by generating consistent images and videos.</td>
|
| 73 |
+
</tr>
|
| 74 |
+
<tr style="border-top: 2px solid black">
|
| 75 |
+
<td><a href="https://github.com/cumulo-autumn/StreamDiffusion"> StreamDiffusion </a></td>
|
| 76 |
+
<td>A Pipeline-Level Solution for Real-Time Interactive Generation</td>
|
| 77 |
+
</tr>
|
| 78 |
+
<tr style="border-top: 2px solid black">
|
| 79 |
+
<td><a href="https://github.com/Netwrck/stable-diffusion-server"> Stable Diffusion Server </a></td>
|
| 80 |
+
<td>A server configured for Inpainting/Generation/img2img with one stable diffusion model</td>
|
| 81 |
+
</tr>
|
| 82 |
+
<tr style="border-top: 2px solid black">
|
| 83 |
+
<td><a href="https://github.com/suzukimain/auto_diffusers"> Model Search </a></td>
|
| 84 |
+
<td>Search models on Civitai and Hugging Face</td>
|
| 85 |
+
</tr>
|
| 86 |
+
<tr style="border-top: 2px solid black">
|
| 87 |
+
<td><a href="https://github.com/beinsezii/skrample"> Skrample </a></td>
|
| 88 |
+
<td>Fully modular scheduler functions with 1st class diffusers integration.</td>
|
| 89 |
+
</tr>
|
| 90 |
+
</table>
|
tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/conceptual/contribution.md
ADDED
|
@@ -0,0 +1,568 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# How to contribute to Diffusers 🧨
|
| 14 |
+
|
| 15 |
+
We ❤️ contributions from the open-source community! Everyone is welcome, and all types of participation –not just code– are valued and appreciated. Answering questions, helping others, reaching out, and improving the documentation are all immensely valuable to the community, so don't be afraid and get involved if you're up for it!
|
| 16 |
+
|
| 17 |
+
Everyone is encouraged to start by saying 👋 in our public Discord channel. We discuss the latest trends in diffusion models, ask questions, show off personal projects, help each other with contributions, or just hang out ☕. <a href="https://Discord.gg/G7tWnz98XR"><img alt="Join us on Discord" src="https://img.shields.io/discord/823813159592001537?color=5865F2&logo=discord&logoColor=white"></a>
|
| 18 |
+
|
| 19 |
+
Whichever way you choose to contribute, we strive to be part of an open, welcoming, and kind community. Please, read our [code of conduct](https://github.com/huggingface/diffusers/blob/main/CODE_OF_CONDUCT.md) and be mindful to respect it during your interactions. We also recommend you become familiar with the [ethical guidelines](https://huggingface.co/docs/diffusers/conceptual/ethical_guidelines) that guide our project and ask you to adhere to the same principles of transparency and responsibility.
|
| 20 |
+
|
| 21 |
+
We enormously value feedback from the community, so please do not be afraid to speak up if you believe you have valuable feedback that can help improve the library - every message, comment, issue, and pull request (PR) is read and considered.
|
| 22 |
+
|
| 23 |
+
## Overview
|
| 24 |
+
|
| 25 |
+
You can contribute in many ways ranging from answering questions on issues and discussions to adding new diffusion models to the core library.
|
| 26 |
+
|
| 27 |
+
In the following, we give an overview of different ways to contribute, ranked by difficulty in ascending order. All of them are valuable to the community.
|
| 28 |
+
|
| 29 |
+
* 1. Asking and answering questions on [the Diffusers discussion forum](https://discuss.huggingface.co/c/discussion-related-to-httpsgithubcomhuggingfacediffusers) or on [Discord](https://discord.gg/G7tWnz98XR).
|
| 30 |
+
* 2. Opening new issues on [the GitHub Issues tab](https://github.com/huggingface/diffusers/issues/new/choose) or new discussions on [the GitHub Discussions tab](https://github.com/huggingface/diffusers/discussions/new/choose).
|
| 31 |
+
* 3. Answering issues on [the GitHub Issues tab](https://github.com/huggingface/diffusers/issues) or discussions on [the GitHub Discussions tab](https://github.com/huggingface/diffusers/discussions).
|
| 32 |
+
* 4. Fix a simple issue, marked by the "Good first issue" label, see [here](https://github.com/huggingface/diffusers/issues?q=is%3Aopen+is%3Aissue+label%3A%22good+first+issue%22).
|
| 33 |
+
* 5. Contribute to the [documentation](https://github.com/huggingface/diffusers/tree/main/docs/source).
|
| 34 |
+
* 6. Contribute a [Community Pipeline](https://github.com/huggingface/diffusers/issues?q=is%3Aopen+is%3Aissue+label%3Acommunity-examples).
|
| 35 |
+
* 7. Contribute to the [examples](https://github.com/huggingface/diffusers/tree/main/examples).
|
| 36 |
+
* 8. Fix a more difficult issue, marked by the "Good second issue" label, see [here](https://github.com/huggingface/diffusers/issues?q=is%3Aopen+is%3Aissue+label%3A%22Good+second+issue%22).
|
| 37 |
+
* 9. Add a new pipeline, model, or scheduler, see ["New Pipeline/Model"](https://github.com/huggingface/diffusers/issues?q=is%3Aopen+is%3Aissue+label%3A%22New+pipeline%2Fmodel%22) and ["New scheduler"](https://github.com/huggingface/diffusers/issues?q=is%3Aopen+is%3Aissue+label%3A%22New+scheduler%22) issues. For this contribution, please have a look at [Design Philosophy](https://github.com/huggingface/diffusers/blob/main/PHILOSOPHY.md).
|
| 38 |
+
|
| 39 |
+
As said before, **all contributions are valuable to the community**.
|
| 40 |
+
In the following, we will explain each contribution a bit more in detail.
|
| 41 |
+
|
| 42 |
+
For all contributions 4 - 9, you will need to open a PR. It is explained in detail how to do so in [Opening a pull request](#how-to-open-a-pr).
|
| 43 |
+
|
| 44 |
+
### 1. Asking and answering questions on the Diffusers discussion forum or on the Diffusers Discord
|
| 45 |
+
|
| 46 |
+
Any question or comment related to the Diffusers library can be asked on the [discussion forum](https://discuss.huggingface.co/c/discussion-related-to-httpsgithubcomhuggingfacediffusers/) or on [Discord](https://discord.gg/G7tWnz98XR). Such questions and comments include (but are not limited to):
|
| 47 |
+
- Reports of training or inference experiments in an attempt to share knowledge
|
| 48 |
+
- Presentation of personal projects
|
| 49 |
+
- Questions to non-official training examples
|
| 50 |
+
- Project proposals
|
| 51 |
+
- General feedback
|
| 52 |
+
- Paper summaries
|
| 53 |
+
- Asking for help on personal projects that build on top of the Diffusers library
|
| 54 |
+
- General questions
|
| 55 |
+
- Ethical questions regarding diffusion models
|
| 56 |
+
- ...
|
| 57 |
+
|
| 58 |
+
Every question that is asked on the forum or on Discord actively encourages the community to publicly
|
| 59 |
+
share knowledge and might very well help a beginner in the future who has the same question you're
|
| 60 |
+
having. Please do pose any questions you might have.
|
| 61 |
+
In the same spirit, you are of immense help to the community by answering such questions because this way you are publicly documenting knowledge for everybody to learn from.
|
| 62 |
+
|
| 63 |
+
**Please** keep in mind that the more effort you put into asking or answering a question, the higher
|
| 64 |
+
the quality of the publicly documented knowledge. In the same way, well-posed and well-answered questions create a high-quality knowledge database accessible to everybody, while badly posed questions or answers reduce the overall quality of the public knowledge database.
|
| 65 |
+
In short, a high quality question or answer is *precise*, *concise*, *relevant*, *easy-to-understand*, *accessible*, and *well-formatted/well-posed*. For more information, please have a look through the [How to write a good issue](#how-to-write-a-good-issue) section.
|
| 66 |
+
|
| 67 |
+
**NOTE about channels**:
|
| 68 |
+
[*The forum*](https://discuss.huggingface.co/c/discussion-related-to-httpsgithubcomhuggingfacediffusers/63) is much better indexed by search engines, such as Google. Posts are ranked by popularity rather than chronologically. Hence, it's easier to look up questions and answers that we posted some time ago.
|
| 69 |
+
In addition, questions and answers posted in the forum can easily be linked to.
|
| 70 |
+
In contrast, *Discord* has a chat-like format that invites fast back-and-forth communication.
|
| 71 |
+
While it will most likely take less time for you to get an answer to your question on Discord, your
|
| 72 |
+
question won't be visible anymore over time. Also, it's much harder to find information that was posted a while back on Discord. We therefore strongly recommend using the forum for high-quality questions and answers in an attempt to create long-lasting knowledge for the community. If discussions on Discord lead to very interesting answers and conclusions, we recommend posting the results on the forum to make the information more available for future readers.
|
| 73 |
+
|
| 74 |
+
### 2. Opening new issues on the GitHub issues tab
|
| 75 |
+
|
| 76 |
+
The 🧨 Diffusers library is robust and reliable thanks to the users who notify us of
|
| 77 |
+
the problems they encounter. So thank you for reporting an issue.
|
| 78 |
+
|
| 79 |
+
Remember, GitHub issues are reserved for technical questions directly related to the Diffusers library, bug reports, feature requests, or feedback on the library design.
|
| 80 |
+
|
| 81 |
+
In a nutshell, this means that everything that is **not** related to the **code of the Diffusers library** (including the documentation) should **not** be asked on GitHub, but rather on either the [forum](https://discuss.huggingface.co/c/discussion-related-to-httpsgithubcomhuggingfacediffusers/63) or [Discord](https://discord.gg/G7tWnz98XR).
|
| 82 |
+
|
| 83 |
+
**Please consider the following guidelines when opening a new issue**:
|
| 84 |
+
- Make sure you have searched whether your issue has already been asked before (use the search bar on GitHub under Issues).
|
| 85 |
+
- Please never report a new issue on another (related) issue. If another issue is highly related, please
|
| 86 |
+
open a new issue nevertheless and link to the related issue.
|
| 87 |
+
- Make sure your issue is written in English. Please use one of the great, free online translation services, such as [DeepL](https://www.deepl.com/translator) to translate from your native language to English if you are not comfortable in English.
|
| 88 |
+
- Check whether your issue might be solved by updating to the newest Diffusers version. Before posting your issue, please make sure that `python -c "import diffusers; print(diffusers.__version__)"` is higher or matches the latest Diffusers version.
|
| 89 |
+
- Remember that the more effort you put into opening a new issue, the higher the quality of your answer will be and the better the overall quality of the Diffusers issues.
|
| 90 |
+
|
| 91 |
+
New issues usually include the following.
|
| 92 |
+
|
| 93 |
+
#### 2.1. Reproducible, minimal bug reports
|
| 94 |
+
|
| 95 |
+
A bug report should always have a reproducible code snippet and be as minimal and concise as possible.
|
| 96 |
+
This means in more detail:
|
| 97 |
+
- Narrow the bug down as much as you can, **do not just dump your whole code file**.
|
| 98 |
+
- Format your code.
|
| 99 |
+
- Do not include any external libraries except for Diffusers depending on them.
|
| 100 |
+
- **Always** provide all necessary information about your environment; for this, you can run: `diffusers-cli env` in your shell and copy-paste the displayed information to the issue.
|
| 101 |
+
- Explain the issue. If the reader doesn't know what the issue is and why it is an issue, (s)he cannot solve it.
|
| 102 |
+
- **Always** make sure the reader can reproduce your issue with as little effort as possible. If your code snippet cannot be run because of missing libraries or undefined variables, the reader cannot help you. Make sure your reproducible code snippet is as minimal as possible and can be copy-pasted into a simple Python shell.
|
| 103 |
+
- If in order to reproduce your issue a model and/or dataset is required, make sure the reader has access to that model or dataset. You can always upload your model or dataset to the [Hub](https://huggingface.co) to make it easily downloadable. Try to keep your model and dataset as small as possible, to make the reproduction of your issue as effortless as possible.
|
| 104 |
+
|
| 105 |
+
For more information, please have a look through the [How to write a good issue](#how-to-write-a-good-issue) section.
|
| 106 |
+
|
| 107 |
+
You can open a bug report [here](https://github.com/huggingface/diffusers/issues/new?assignees=&labels=bug&projects=&template=bug-report.yml).
|
| 108 |
+
|
| 109 |
+
#### 2.2. Feature requests
|
| 110 |
+
|
| 111 |
+
A world-class feature request addresses the following points:
|
| 112 |
+
|
| 113 |
+
1. Motivation first:
|
| 114 |
+
* Is it related to a problem/frustration with the library? If so, please explain
|
| 115 |
+
why. Providing a code snippet that demonstrates the problem is best.
|
| 116 |
+
* Is it related to something you would need for a project? We'd love to hear
|
| 117 |
+
about it!
|
| 118 |
+
* Is it something you worked on and think could benefit the community?
|
| 119 |
+
Awesome! Tell us what problem it solved for you.
|
| 120 |
+
2. Write a *full paragraph* describing the feature;
|
| 121 |
+
3. Provide a **code snippet** that demonstrates its future use;
|
| 122 |
+
4. In case this is related to a paper, please attach a link;
|
| 123 |
+
5. Attach any additional information (drawings, screenshots, etc.) you think may help.
|
| 124 |
+
|
| 125 |
+
You can open a feature request [here](https://github.com/huggingface/diffusers/issues/new?assignees=&labels=&template=feature_request.md&title=).
|
| 126 |
+
|
| 127 |
+
#### 2.3 Feedback
|
| 128 |
+
|
| 129 |
+
Feedback about the library design and why it is good or not good helps the core maintainers immensely to build a user-friendly library. To understand the philosophy behind the current design philosophy, please have a look [here](https://huggingface.co/docs/diffusers/conceptual/philosophy). If you feel like a certain design choice does not fit with the current design philosophy, please explain why and how it should be changed. If a certain design choice follows the design philosophy too much, hence restricting use cases, explain why and how it should be changed.
|
| 130 |
+
If a certain design choice is very useful for you, please also leave a note as this is great feedback for future design decisions.
|
| 131 |
+
|
| 132 |
+
You can open an issue about feedback [here](https://github.com/huggingface/diffusers/issues/new?assignees=&labels=&template=feedback.md&title=).
|
| 133 |
+
|
| 134 |
+
#### 2.4 Technical questions
|
| 135 |
+
|
| 136 |
+
Technical questions are mainly about why certain code of the library was written in a certain way, or what a certain part of the code does. Please make sure to link to the code in question and please provide details on
|
| 137 |
+
why this part of the code is difficult to understand.
|
| 138 |
+
|
| 139 |
+
You can open an issue about a technical question [here](https://github.com/huggingface/diffusers/issues/new?assignees=&labels=bug&template=bug-report.yml).
|
| 140 |
+
|
| 141 |
+
#### 2.5 Proposal to add a new model, scheduler, or pipeline
|
| 142 |
+
|
| 143 |
+
If the diffusion model community released a new model, pipeline, or scheduler that you would like to see in the Diffusers library, please provide the following information:
|
| 144 |
+
|
| 145 |
+
* Short description of the diffusion pipeline, model, or scheduler and link to the paper or public release.
|
| 146 |
+
* Link to any of its open-source implementation(s).
|
| 147 |
+
* Link to the model weights if they are available.
|
| 148 |
+
|
| 149 |
+
If you are willing to contribute to the model yourself, let us know so we can best guide you. Also, don't forget
|
| 150 |
+
to tag the original author of the component (model, scheduler, pipeline, etc.) by GitHub handle if you can find it.
|
| 151 |
+
|
| 152 |
+
You can open a request for a model/pipeline/scheduler [here](https://github.com/huggingface/diffusers/issues/new?assignees=&labels=New+model%2Fpipeline%2Fscheduler&template=new-model-addition.yml).
|
| 153 |
+
|
| 154 |
+
### 3. Answering issues on the GitHub issues tab
|
| 155 |
+
|
| 156 |
+
Answering issues on GitHub might require some technical knowledge of Diffusers, but we encourage everybody to give it a try even if you are not 100% certain that your answer is correct.
|
| 157 |
+
Some tips to give a high-quality answer to an issue:
|
| 158 |
+
- Be as concise and minimal as possible.
|
| 159 |
+
- Stay on topic. An answer to the issue should concern the issue and only the issue.
|
| 160 |
+
- Provide links to code, papers, or other sources that prove or encourage your point.
|
| 161 |
+
- Answer in code. If a simple code snippet is the answer to the issue or shows how the issue can be solved, please provide a fully reproducible code snippet.
|
| 162 |
+
|
| 163 |
+
Also, many issues tend to be simply off-topic, duplicates of other issues, or irrelevant. It is of great
|
| 164 |
+
help to the maintainers if you can answer such issues, encouraging the author of the issue to be
|
| 165 |
+
more precise, provide the link to a duplicated issue or redirect them to [the forum](https://discuss.huggingface.co/c/discussion-related-to-httpsgithubcomhuggingfacediffusers/63) or [Discord](https://discord.gg/G7tWnz98XR).
|
| 166 |
+
|
| 167 |
+
If you have verified that the issued bug report is correct and requires a correction in the source code,
|
| 168 |
+
please have a look at the next sections.
|
| 169 |
+
|
| 170 |
+
For all of the following contributions, you will need to open a PR. It is explained in detail how to do so in the [Opening a pull request](#how-to-open-a-pr) section.
|
| 171 |
+
|
| 172 |
+
### 4. Fixing a "Good first issue"
|
| 173 |
+
|
| 174 |
+
*Good first issues* are marked by the [Good first issue](https://github.com/huggingface/diffusers/issues?q=is%3Aopen+is%3Aissue+label%3A%22good+first+issue%22) label. Usually, the issue already
|
| 175 |
+
explains how a potential solution should look so that it is easier to fix.
|
| 176 |
+
If the issue hasn't been closed and you would like to try to fix this issue, you can just leave a message "I would like to try this issue.". There are usually three scenarios:
|
| 177 |
+
- a.) The issue description already proposes a fix. In this case and if the solution makes sense to you, you can open a PR or draft PR to fix it.
|
| 178 |
+
- b.) The issue description does not propose a fix. In this case, you can ask what a proposed fix could look like and someone from the Diffusers team should answer shortly. If you have a good idea of how to fix it, feel free to directly open a PR.
|
| 179 |
+
- c.) There is already an open PR to fix the issue, but the issue hasn't been closed yet. If the PR has gone stale, you can simply open a new PR and link to the stale PR. PRs often go stale if the original contributor who wanted to fix the issue suddenly cannot find the time anymore to proceed. This often happens in open-source and is very normal. In this case, the community will be very happy if you give it a new try and leverage the knowledge of the existing PR. If there is already a PR and it is active, you can help the author by giving suggestions, reviewing the PR or even asking whether you can contribute to the PR.
|
| 180 |
+
|
| 181 |
+
|
| 182 |
+
### 5. Contribute to the documentation
|
| 183 |
+
|
| 184 |
+
A good library **always** has good documentation! The official documentation is often one of the first points of contact for new users of the library, and therefore contributing to the documentation is a **highly
|
| 185 |
+
valuable contribution**.
|
| 186 |
+
|
| 187 |
+
Contributing to the library can have many forms:
|
| 188 |
+
|
| 189 |
+
- Correcting spelling or grammatical errors.
|
| 190 |
+
- Correct incorrect formatting of the docstring. If you see that the official documentation is weirdly displayed or a link is broken, we would be very happy if you take some time to correct it.
|
| 191 |
+
- Correct the shape or dimensions of a docstring input or output tensor.
|
| 192 |
+
- Clarify documentation that is hard to understand or incorrect.
|
| 193 |
+
- Update outdated code examples.
|
| 194 |
+
- Translating the documentation to another language.
|
| 195 |
+
|
| 196 |
+
Anything displayed on [the official Diffusers doc page](https://huggingface.co/docs/diffusers/index) is part of the official documentation and can be corrected, adjusted in the respective [documentation source](https://github.com/huggingface/diffusers/tree/main/docs/source).
|
| 197 |
+
|
| 198 |
+
Please have a look at [this page](https://github.com/huggingface/diffusers/tree/main/docs) on how to verify changes made to the documentation locally.
|
| 199 |
+
|
| 200 |
+
### 6. Contribute a community pipeline
|
| 201 |
+
|
| 202 |
+
> [!TIP]
|
| 203 |
+
> Read the [Community pipelines](../using-diffusers/custom_pipeline_overview#community-pipelines) guide to learn more about the difference between a GitHub and Hugging Face Hub community pipeline. If you're interested in why we have community pipelines, take a look at GitHub Issue [#841](https://github.com/huggingface/diffusers/issues/841) (basically, we can't maintain all the possible ways diffusion models can be used for inference but we also don't want to prevent the community from building them).
|
| 204 |
+
|
| 205 |
+
Contributing a community pipeline is a great way to share your creativity and work with the community. It lets you build on top of the [`DiffusionPipeline`] so that anyone can load and use it by setting the `custom_pipeline` parameter. This section will walk you through how to create a simple pipeline where the UNet only does a single forward pass and calls the scheduler once (a "one-step" pipeline).
|
| 206 |
+
|
| 207 |
+
1. Create a one_step_unet.py file for your community pipeline. This file can contain whatever package you want to use as long as it's installed by the user. Make sure you only have one pipeline class that inherits from [`DiffusionPipeline`] to load model weights and the scheduler configuration from the Hub. Add a UNet and scheduler to the `__init__` function.
|
| 208 |
+
|
| 209 |
+
You should also add the `register_modules` function to ensure your pipeline and its components can be saved with [`~DiffusionPipeline.save_pretrained`].
|
| 210 |
+
|
| 211 |
+
```py
|
| 212 |
+
from diffusers import DiffusionPipeline
|
| 213 |
+
import torch
|
| 214 |
+
|
| 215 |
+
class UnetSchedulerOneForwardPipeline(DiffusionPipeline):
|
| 216 |
+
def __init__(self, unet, scheduler):
|
| 217 |
+
super().__init__()
|
| 218 |
+
|
| 219 |
+
self.register_modules(unet=unet, scheduler=scheduler)
|
| 220 |
+
```
|
| 221 |
+
|
| 222 |
+
1. In the forward pass (which we recommend defining as `__call__`), you can add any feature you'd like. For the "one-step" pipeline, create a random image and call the UNet and scheduler once by setting `timestep=1`.
|
| 223 |
+
|
| 224 |
+
```py
|
| 225 |
+
from diffusers import DiffusionPipeline
|
| 226 |
+
import torch
|
| 227 |
+
|
| 228 |
+
class UnetSchedulerOneForwardPipeline(DiffusionPipeline):
|
| 229 |
+
def __init__(self, unet, scheduler):
|
| 230 |
+
super().__init__()
|
| 231 |
+
|
| 232 |
+
self.register_modules(unet=unet, scheduler=scheduler)
|
| 233 |
+
|
| 234 |
+
def __call__(self):
|
| 235 |
+
image = torch.randn(
|
| 236 |
+
(1, self.unet.config.in_channels, self.unet.config.sample_size, self.unet.config.sample_size),
|
| 237 |
+
)
|
| 238 |
+
timestep = 1
|
| 239 |
+
|
| 240 |
+
model_output = self.unet(image, timestep).sample
|
| 241 |
+
scheduler_output = self.scheduler.step(model_output, timestep, image).prev_sample
|
| 242 |
+
|
| 243 |
+
return scheduler_output
|
| 244 |
+
```
|
| 245 |
+
|
| 246 |
+
Now you can run the pipeline by passing a UNet and scheduler to it or load pretrained weights if the pipeline structure is identical.
|
| 247 |
+
|
| 248 |
+
```py
|
| 249 |
+
from diffusers import DDPMScheduler, UNet2DModel
|
| 250 |
+
|
| 251 |
+
scheduler = DDPMScheduler()
|
| 252 |
+
unet = UNet2DModel()
|
| 253 |
+
|
| 254 |
+
pipeline = UnetSchedulerOneForwardPipeline(unet=unet, scheduler=scheduler)
|
| 255 |
+
output = pipeline()
|
| 256 |
+
# load pretrained weights
|
| 257 |
+
pipeline = UnetSchedulerOneForwardPipeline.from_pretrained("google/ddpm-cifar10-32", use_safetensors=True)
|
| 258 |
+
output = pipeline()
|
| 259 |
+
```
|
| 260 |
+
|
| 261 |
+
You can either share your pipeline as a GitHub community pipeline or Hub community pipeline.
|
| 262 |
+
|
| 263 |
+
<hfoptions id="pipeline type">
|
| 264 |
+
<hfoption id="GitHub pipeline">
|
| 265 |
+
|
| 266 |
+
Share your GitHub pipeline by opening a pull request on the Diffusers [repository](https://github.com/huggingface/diffusers) and add the one_step_unet.py file to the [examples/community](https://github.com/huggingface/diffusers/tree/main/examples/community) subfolder.
|
| 267 |
+
|
| 268 |
+
</hfoption>
|
| 269 |
+
<hfoption id="Hub pipeline">
|
| 270 |
+
|
| 271 |
+
Share your Hub pipeline by creating a model repository on the Hub and uploading the one_step_unet.py file to it.
|
| 272 |
+
|
| 273 |
+
</hfoption>
|
| 274 |
+
</hfoptions>
|
| 275 |
+
|
| 276 |
+
### 7. Contribute to training examples
|
| 277 |
+
|
| 278 |
+
Diffusers examples are a collection of training scripts that reside in [examples](https://github.com/huggingface/diffusers/tree/main/examples).
|
| 279 |
+
|
| 280 |
+
We support two types of training examples:
|
| 281 |
+
|
| 282 |
+
- Official training examples
|
| 283 |
+
- Research training examples
|
| 284 |
+
|
| 285 |
+
Research training examples are located in [examples/research_projects](https://github.com/huggingface/diffusers/tree/main/examples/research_projects) whereas official training examples include all folders under [examples](https://github.com/huggingface/diffusers/tree/main/examples) except the `research_projects` and `community` folders.
|
| 286 |
+
The official training examples are maintained by the Diffusers' core maintainers whereas the research training examples are maintained by the community.
|
| 287 |
+
This is because of the same reasons put forward in [6. Contribute a community pipeline](#6-contribute-a-community-pipeline) for official pipelines vs. community pipelines: It is not feasible for the core maintainers to maintain all possible training methods for diffusion models.
|
| 288 |
+
If the Diffusers core maintainers and the community consider a certain training paradigm to be too experimental or not popular enough, the corresponding training code should be put in the `research_projects` folder and maintained by the author.
|
| 289 |
+
|
| 290 |
+
Both official training and research examples consist of a directory that contains one or more training scripts, a `requirements.txt` file, and a `README.md` file. In order for the user to make use of the
|
| 291 |
+
training examples, it is required to clone the repository:
|
| 292 |
+
|
| 293 |
+
```bash
|
| 294 |
+
git clone https://github.com/huggingface/diffusers
|
| 295 |
+
```
|
| 296 |
+
|
| 297 |
+
as well as to install all additional dependencies required for training:
|
| 298 |
+
|
| 299 |
+
```bash
|
| 300 |
+
cd diffusers
|
| 301 |
+
pip install -r examples/<your-example-folder>/requirements.txt
|
| 302 |
+
```
|
| 303 |
+
|
| 304 |
+
Therefore when adding an example, the `requirements.txt` file shall define all pip dependencies required for your training example so that once all those are installed, the user can run the example's training script. See, for example, the [DreamBooth `requirements.txt` file](https://github.com/huggingface/diffusers/blob/main/examples/dreambooth/requirements.txt).
|
| 305 |
+
|
| 306 |
+
Training examples of the Diffusers library should adhere to the following philosophy:
|
| 307 |
+
- All the code necessary to run the examples should be found in a single Python file.
|
| 308 |
+
- One should be able to run the example from the command line with `python <your-example>.py --args`.
|
| 309 |
+
- Examples should be kept simple and serve as **an example** on how to use Diffusers for training. The purpose of example scripts is **not** to create state-of-the-art diffusion models, but rather to reproduce known training schemes without adding too much custom logic. As a byproduct of this point, our examples also strive to serve as good educational materials.
|
| 310 |
+
|
| 311 |
+
To contribute an example, it is highly recommended to look at already existing examples such as [dreambooth](https://github.com/huggingface/diffusers/blob/main/examples/dreambooth/train_dreambooth.py) to get an idea of how they should look like.
|
| 312 |
+
We strongly advise contributors to make use of the [Accelerate library](https://github.com/huggingface/accelerate) as it's tightly integrated
|
| 313 |
+
with Diffusers.
|
| 314 |
+
Once an example script works, please make sure to add a comprehensive `README.md` that states how to use the example exactly. This README should include:
|
| 315 |
+
- An example command on how to run the example script as shown [here](https://github.com/huggingface/diffusers/tree/main/examples/dreambooth#running-locally-with-pytorch).
|
| 316 |
+
- A link to some training results (logs, models, etc.) that show what the user can expect as shown [here](https://api.wandb.ai/report/patrickvonplaten/xm6cd5q5).
|
| 317 |
+
- If you are adding a non-official/research training example, **please don't forget** to add a sentence that you are maintaining this training example which includes your git handle as shown [here](https://github.com/huggingface/diffusers/tree/main/examples/research_projects/intel_opts#diffusers-examples-with-intel-optimizations).
|
| 318 |
+
|
| 319 |
+
If you are contributing to the official training examples, please also make sure to add a test to its folder such as [examples/dreambooth/test_dreambooth.py](https://github.com/huggingface/diffusers/blob/main/examples/dreambooth/test_dreambooth.py). This is not necessary for non-official training examples.
|
| 320 |
+
|
| 321 |
+
### 8. Fixing a "Good second issue"
|
| 322 |
+
|
| 323 |
+
*Good second issues* are marked by the [Good second issue](https://github.com/huggingface/diffusers/issues?q=is%3Aopen+is%3Aissue+label%3A%22Good+second+issue%22) label. Good second issues are
|
| 324 |
+
usually more complicated to solve than [Good first issues](https://github.com/huggingface/diffusers/issues?q=is%3Aopen+is%3Aissue+label%3A%22good+first+issue%22).
|
| 325 |
+
The issue description usually gives less guidance on how to fix the issue and requires
|
| 326 |
+
a decent understanding of the library by the interested contributor.
|
| 327 |
+
If you are interested in tackling a good second issue, feel free to open a PR to fix it and link the PR to the issue. If you see that a PR has already been opened for this issue but did not get merged, have a look to understand why it wasn't merged and try to open an improved PR.
|
| 328 |
+
Good second issues are usually more difficult to get merged compared to good first issues, so don't hesitate to ask for help from the core maintainers. If your PR is almost finished the core maintainers can also jump into your PR and commit to it in order to get it merged.
|
| 329 |
+
|
| 330 |
+
### 9. Adding pipelines, models, schedulers
|
| 331 |
+
|
| 332 |
+
Pipelines, models, and schedulers are the most important pieces of the Diffusers library.
|
| 333 |
+
They provide easy access to state-of-the-art diffusion technologies and thus allow the community to
|
| 334 |
+
build powerful generative AI applications.
|
| 335 |
+
|
| 336 |
+
By adding a new model, pipeline, or scheduler you might enable a new powerful use case for any of the user interfaces relying on Diffusers which can be of immense value for the whole generative AI ecosystem.
|
| 337 |
+
|
| 338 |
+
Diffusers has a couple of open feature requests for all three components - feel free to gloss over them
|
| 339 |
+
if you don't know yet what specific component you would like to add:
|
| 340 |
+
- [Model or pipeline](https://github.com/huggingface/diffusers/issues?q=is%3Aopen+is%3Aissue+label%3A%22New+pipeline%2Fmodel%22)
|
| 341 |
+
- [Scheduler](https://github.com/huggingface/diffusers/issues?q=is%3Aopen+is%3Aissue+label%3A%22New+scheduler%22)
|
| 342 |
+
|
| 343 |
+
Before adding any of the three components, it is strongly recommended that you give the [Philosophy guide](philosophy) a read to better understand the design of any of the three components. Please be aware that we cannot merge model, scheduler, or pipeline additions that strongly diverge from our design philosophy
|
| 344 |
+
as it will lead to API inconsistencies. If you fundamentally disagree with a design choice, please open a [Feedback issue](https://github.com/huggingface/diffusers/issues/new?assignees=&labels=&template=feedback.md&title=) instead so that it can be discussed whether a certain design pattern/design choice shall be changed everywhere in the library and whether we shall update our design philosophy. Consistency across the library is very important for us.
|
| 345 |
+
|
| 346 |
+
Please make sure to add links to the original codebase/paper to the PR and ideally also ping the original author directly on the PR so that they can follow the progress and potentially help with questions.
|
| 347 |
+
|
| 348 |
+
If you are unsure or stuck in the PR, don't hesitate to leave a message to ask for a first review or help.
|
| 349 |
+
|
| 350 |
+
#### Copied from mechanism
|
| 351 |
+
|
| 352 |
+
A unique and important feature to understand when adding any pipeline, model or scheduler code is the `# Copied from` mechanism. You'll see this all over the Diffusers codebase, and the reason we use it is to keep the codebase easy to understand and maintain. Marking code with the `# Copied from` mechanism forces the marked code to be identical to the code it was copied from. This makes it easy to update and propagate changes across many files whenever you run `make fix-copies`.
|
| 353 |
+
|
| 354 |
+
For example, in the code example below, [`~diffusers.pipelines.stable_diffusion.StableDiffusionPipelineOutput`] is the original code and `AltDiffusionPipelineOutput` uses the `# Copied from` mechanism to copy it. The only difference is changing the class prefix from `Stable` to `Alt`.
|
| 355 |
+
|
| 356 |
+
```py
|
| 357 |
+
# Copied from diffusers.pipelines.stable_diffusion.pipeline_output.StableDiffusionPipelineOutput with Stable->Alt
|
| 358 |
+
class AltDiffusionPipelineOutput(BaseOutput):
|
| 359 |
+
"""
|
| 360 |
+
Output class for Alt Diffusion pipelines.
|
| 361 |
+
|
| 362 |
+
Args:
|
| 363 |
+
images (`List[PIL.Image.Image]` or `np.ndarray`)
|
| 364 |
+
List of denoised PIL images of length `batch_size` or NumPy array of shape `(batch_size, height, width,
|
| 365 |
+
num_channels)`.
|
| 366 |
+
nsfw_content_detected (`List[bool]`)
|
| 367 |
+
List indicating whether the corresponding generated image contains "not-safe-for-work" (nsfw) content or
|
| 368 |
+
`None` if safety checking could not be performed.
|
| 369 |
+
"""
|
| 370 |
+
```
|
| 371 |
+
|
| 372 |
+
To learn more, read this section of the [~Don't~ Repeat Yourself*](https://huggingface.co/blog/transformers-design-philosophy#4-machine-learning-models-are-static) blog post.
|
| 373 |
+
|
| 374 |
+
## How to write a good issue
|
| 375 |
+
|
| 376 |
+
**The better your issue is written, the higher the chances that it will be quickly resolved.**
|
| 377 |
+
|
| 378 |
+
1. Make sure that you've used the correct template for your issue. You can pick between *Bug Report*, *Feature Request*, *Feedback about API Design*, *New model/pipeline/scheduler addition*, *Forum*, or a blank issue. Make sure to pick the correct one when opening [a new issue](https://github.com/huggingface/diffusers/issues/new/choose).
|
| 379 |
+
2. **Be precise**: Give your issue a fitting title. Try to formulate your issue description as simple as possible. The more precise you are when submitting an issue, the less time it takes to understand the issue and potentially solve it. Make sure to open an issue for one issue only and not for multiple issues. If you found multiple issues, simply open multiple issues. If your issue is a bug, try to be as precise as possible about what bug it is - you should not just write "Error in diffusers".
|
| 380 |
+
3. **Reproducibility**: No reproducible code snippet == no solution. If you encounter a bug, maintainers **have to be able to reproduce** it. Make sure that you include a code snippet that can be copy-pasted into a Python interpreter to reproduce the issue. Make sure that your code snippet works, *i.e.* that there are no missing imports or missing links to images, ... Your issue should contain an error message **and** a code snippet that can be copy-pasted without any changes to reproduce the exact same error message. If your issue is using local model weights or local data that cannot be accessed by the reader, the issue cannot be solved. If you cannot share your data or model, try to make a dummy model or dummy data.
|
| 381 |
+
4. **Minimalistic**: Try to help the reader as much as you can to understand the issue as quickly as possible by staying as concise as possible. Remove all code / all information that is irrelevant to the issue. If you have found a bug, try to create the easiest code example you can to demonstrate your issue, do not just dump your whole workflow into the issue as soon as you have found a bug. E.g., if you train a model and get an error at some point during the training, you should first try to understand what part of the training code is responsible for the error and try to reproduce it with a couple of lines. Try to use dummy data instead of full datasets.
|
| 382 |
+
5. Add links. If you are referring to a certain naming, method, or model make sure to provide a link so that the reader can better understand what you mean. If you are referring to a specific PR or issue, make sure to link it to your issue. Do not assume that the reader knows what you are talking about. The more links you add to your issue the better.
|
| 383 |
+
6. Formatting. Make sure to nicely format your issue by formatting code into Python code syntax, and error messages into normal code syntax. See the [official GitHub formatting docs](https://docs.github.com/en/get-started/writing-on-github/getting-started-with-writing-and-formatting-on-github/basic-writing-and-formatting-syntax) for more information.
|
| 384 |
+
7. Think of your issue not as a ticket to be solved, but rather as a beautiful entry to a well-written encyclopedia. Every added issue is a contribution to publicly available knowledge. By adding a nicely written issue you not only make it easier for maintainers to solve your issue, but you are helping the whole community to better understand a certain aspect of the library.
|
| 385 |
+
|
| 386 |
+
## How to write a good PR
|
| 387 |
+
|
| 388 |
+
1. Be a chameleon. Understand existing design patterns and syntax and make sure your code additions flow seamlessly into the existing code base. Pull requests that significantly diverge from existing design patterns or user interfaces will not be merged.
|
| 389 |
+
2. Be laser focused. A pull request should solve one problem and one problem only. Make sure to not fall into the trap of "also fixing another problem while we're adding it". It is much more difficult to review pull requests that solve multiple, unrelated problems at once.
|
| 390 |
+
3. If helpful, try to add a code snippet that displays an example of how your addition can be used.
|
| 391 |
+
4. The title of your pull request should be a summary of its contribution.
|
| 392 |
+
5. If your pull request addresses an issue, please mention the issue number in
|
| 393 |
+
the pull request description to make sure they are linked (and people
|
| 394 |
+
consulting the issue know you are working on it);
|
| 395 |
+
6. To indicate a work in progress please prefix the title with `[WIP]`. These
|
| 396 |
+
are useful to avoid duplicated work, and to differentiate it from PRs ready
|
| 397 |
+
to be merged;
|
| 398 |
+
7. Try to formulate and format your text as explained in [How to write a good issue](#how-to-write-a-good-issue).
|
| 399 |
+
8. Make sure existing tests pass;
|
| 400 |
+
9. Add high-coverage tests. No quality testing = no merge.
|
| 401 |
+
- If you are adding new `@slow` tests, make sure they pass using
|
| 402 |
+
`RUN_SLOW=1 python -m pytest tests/test_my_new_model.py`.
|
| 403 |
+
CircleCI does not run the slow tests, but GitHub Actions does every night!
|
| 404 |
+
10. All public methods must have informative docstrings that work nicely with markdown. See [`pipeline_latent_diffusion.py`](https://github.com/huggingface/diffusers/blob/main/src/diffusers/pipelines/latent_diffusion/pipeline_latent_diffusion.py) for an example.
|
| 405 |
+
11. Due to the rapidly growing repository, it is important to make sure that no files that would significantly weigh down the repository are added. This includes images, videos, and other non-text files. We prefer to leverage a hf.co hosted `dataset` like
|
| 406 |
+
[`hf-internal-testing`](https://huggingface.co/hf-internal-testing) or [huggingface/documentation-images](https://huggingface.co/datasets/huggingface/documentation-images) to place these files.
|
| 407 |
+
If an external contribution, feel free to add the images to your PR and ask a Hugging Face member to migrate your images
|
| 408 |
+
to this dataset.
|
| 409 |
+
|
| 410 |
+
## How to open a PR
|
| 411 |
+
|
| 412 |
+
Before writing code, we strongly advise you to search through the existing PRs or
|
| 413 |
+
issues to make sure that nobody is already working on the same thing. If you are
|
| 414 |
+
unsure, it is always a good idea to open an issue to get some feedback.
|
| 415 |
+
|
| 416 |
+
You will need basic `git` proficiency to be able to contribute to
|
| 417 |
+
🧨 Diffusers. `git` is not the easiest tool to use but it has the greatest
|
| 418 |
+
manual. Type `git --help` in a shell and enjoy. If you prefer books, [Pro
|
| 419 |
+
Git](https://git-scm.com/book/en/v2) is a very good reference.
|
| 420 |
+
|
| 421 |
+
Follow these steps to start contributing ([supported Python versions](https://github.com/huggingface/diffusers/blob/83bc6c94eaeb6f7704a2a428931cf2d9ad973ae9/setup.py#L270)):
|
| 422 |
+
|
| 423 |
+
1. Fork the [repository](https://github.com/huggingface/diffusers) by
|
| 424 |
+
clicking on the 'Fork' button on the repository's page. This creates a copy of the code
|
| 425 |
+
under your GitHub user account.
|
| 426 |
+
|
| 427 |
+
2. Clone your fork to your local disk, and add the base repository as a remote:
|
| 428 |
+
|
| 429 |
+
```bash
|
| 430 |
+
$ git clone git@github.com:<your GitHub handle>/diffusers.git
|
| 431 |
+
$ cd diffusers
|
| 432 |
+
$ git remote add upstream https://github.com/huggingface/diffusers.git
|
| 433 |
+
```
|
| 434 |
+
|
| 435 |
+
3. Create a new branch to hold your development changes:
|
| 436 |
+
|
| 437 |
+
```bash
|
| 438 |
+
$ git checkout -b a-descriptive-name-for-my-changes
|
| 439 |
+
```
|
| 440 |
+
|
| 441 |
+
**Do not** work on the `main` branch.
|
| 442 |
+
|
| 443 |
+
4. Set up a development environment by running the following command in a virtual environment:
|
| 444 |
+
|
| 445 |
+
```bash
|
| 446 |
+
$ pip install -e ".[dev]"
|
| 447 |
+
```
|
| 448 |
+
|
| 449 |
+
If you have already cloned the repo, you might need to `git pull` to get the most recent changes in the
|
| 450 |
+
library.
|
| 451 |
+
|
| 452 |
+
5. Develop the features on your branch.
|
| 453 |
+
|
| 454 |
+
As you work on the features, you should make sure that the test suite
|
| 455 |
+
passes. You should run the tests impacted by your changes like this:
|
| 456 |
+
|
| 457 |
+
```bash
|
| 458 |
+
$ pytest tests/<TEST_TO_RUN>.py
|
| 459 |
+
```
|
| 460 |
+
|
| 461 |
+
Before you run the tests, please make sure you install the dependencies required for testing. You can do so
|
| 462 |
+
with this command:
|
| 463 |
+
|
| 464 |
+
```bash
|
| 465 |
+
$ pip install -e ".[test]"
|
| 466 |
+
```
|
| 467 |
+
|
| 468 |
+
You can also run the full test suite with the following command, but it takes
|
| 469 |
+
a beefy machine to produce a result in a decent amount of time now that
|
| 470 |
+
Diffusers has grown a lot. Here is the command for it:
|
| 471 |
+
|
| 472 |
+
```bash
|
| 473 |
+
$ make test
|
| 474 |
+
```
|
| 475 |
+
|
| 476 |
+
🧨 Diffusers relies on `black` and `isort` to format its source code
|
| 477 |
+
consistently. After you make changes, apply automatic style corrections and code verifications
|
| 478 |
+
that can't be automated in one go with:
|
| 479 |
+
|
| 480 |
+
```bash
|
| 481 |
+
$ make style
|
| 482 |
+
```
|
| 483 |
+
|
| 484 |
+
🧨 Diffusers also uses `ruff` and a few custom scripts to check for coding mistakes. Quality
|
| 485 |
+
control runs in CI, however, you can also run the same checks with:
|
| 486 |
+
|
| 487 |
+
```bash
|
| 488 |
+
$ make quality
|
| 489 |
+
```
|
| 490 |
+
|
| 491 |
+
Once you're happy with your changes, add changed files using `git add` and
|
| 492 |
+
make a commit with `git commit` to record your changes locally:
|
| 493 |
+
|
| 494 |
+
```bash
|
| 495 |
+
$ git add modified_file.py
|
| 496 |
+
$ git commit -m "A descriptive message about your changes."
|
| 497 |
+
```
|
| 498 |
+
|
| 499 |
+
It is a good idea to sync your copy of the code with the original
|
| 500 |
+
repository regularly. This way you can quickly account for changes:
|
| 501 |
+
|
| 502 |
+
```bash
|
| 503 |
+
$ git pull upstream main
|
| 504 |
+
```
|
| 505 |
+
|
| 506 |
+
Push the changes to your account using:
|
| 507 |
+
|
| 508 |
+
```bash
|
| 509 |
+
$ git push -u origin a-descriptive-name-for-my-changes
|
| 510 |
+
```
|
| 511 |
+
|
| 512 |
+
6. Once you are satisfied, go to the
|
| 513 |
+
webpage of your fork on GitHub. Click on 'Pull request' to send your changes
|
| 514 |
+
to the project maintainers for review.
|
| 515 |
+
|
| 516 |
+
7. It's OK if maintainers ask you for changes. It happens to core contributors
|
| 517 |
+
too! So everyone can see the changes in the Pull request, work in your local
|
| 518 |
+
branch and push the changes to your fork. They will automatically appear in
|
| 519 |
+
the pull request.
|
| 520 |
+
|
| 521 |
+
### Tests
|
| 522 |
+
|
| 523 |
+
An extensive test suite is included to test the library behavior and several examples. Library tests can be found in
|
| 524 |
+
the [tests folder](https://github.com/huggingface/diffusers/tree/main/tests).
|
| 525 |
+
|
| 526 |
+
We like `pytest` and `pytest-xdist` because it's faster. From the root of the
|
| 527 |
+
repository, here's how to run tests with `pytest` for the library:
|
| 528 |
+
|
| 529 |
+
```bash
|
| 530 |
+
$ python -m pytest -n auto --dist=loadfile -s -v ./tests/
|
| 531 |
+
```
|
| 532 |
+
|
| 533 |
+
In fact, that's how `make test` is implemented!
|
| 534 |
+
|
| 535 |
+
You can specify a smaller set of tests in order to test only the feature
|
| 536 |
+
you're working on.
|
| 537 |
+
|
| 538 |
+
By default, slow tests are skipped. Set the `RUN_SLOW` environment variable to
|
| 539 |
+
`yes` to run them. This will download many gigabytes of models — make sure you
|
| 540 |
+
have enough disk space and a good Internet connection, or a lot of patience!
|
| 541 |
+
|
| 542 |
+
```bash
|
| 543 |
+
$ RUN_SLOW=yes python -m pytest -n auto --dist=loadfile -s -v ./tests/
|
| 544 |
+
```
|
| 545 |
+
|
| 546 |
+
`unittest` is fully supported, here's how to run tests with it:
|
| 547 |
+
|
| 548 |
+
```bash
|
| 549 |
+
$ python -m unittest discover -s tests -t . -v
|
| 550 |
+
$ python -m unittest discover -s examples -t examples -v
|
| 551 |
+
```
|
| 552 |
+
|
| 553 |
+
### Syncing forked main with upstream (HuggingFace) main
|
| 554 |
+
|
| 555 |
+
To avoid pinging the upstream repository which adds reference notes to each upstream PR and sends unnecessary notifications to the developers involved in these PRs,
|
| 556 |
+
when syncing the main branch of a forked repository, please, follow these steps:
|
| 557 |
+
1. When possible, avoid syncing with the upstream using a branch and PR on the forked repository. Instead, merge directly into the forked main.
|
| 558 |
+
2. If a PR is absolutely necessary, use the following steps after checking out your branch:
|
| 559 |
+
```bash
|
| 560 |
+
$ git checkout -b your-branch-for-syncing
|
| 561 |
+
$ git pull --squash --no-commit upstream main
|
| 562 |
+
$ git commit -m '<your message without GitHub references>'
|
| 563 |
+
$ git push --set-upstream origin your-branch-for-syncing
|
| 564 |
+
```
|
| 565 |
+
|
| 566 |
+
### Style guide
|
| 567 |
+
|
| 568 |
+
For documentation strings, 🧨 Diffusers follows the [Google style](https://google.github.io/styleguide/pyguide.html).
|
tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/conceptual/ethical_guidelines.md
ADDED
|
@@ -0,0 +1,63 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# 🧨 Diffusers’ Ethical Guidelines
|
| 14 |
+
|
| 15 |
+
## Preamble
|
| 16 |
+
|
| 17 |
+
[Diffusers](https://huggingface.co/docs/diffusers/index) provides pre-trained diffusion models and serves as a modular toolbox for inference and training.
|
| 18 |
+
|
| 19 |
+
Given its real case applications in the world and potential negative impacts on society, we think it is important to provide the project with ethical guidelines to guide the development, users’ contributions, and usage of the Diffusers library.
|
| 20 |
+
|
| 21 |
+
The risks associated with using this technology are still being examined, but to name a few: copyrights issues for artists; deep-fake exploitation; sexual content generation in inappropriate contexts; non-consensual impersonation; harmful social biases perpetuating the oppression of marginalized groups.
|
| 22 |
+
We will keep tracking risks and adapt the following guidelines based on the community's responsiveness and valuable feedback.
|
| 23 |
+
|
| 24 |
+
|
| 25 |
+
## Scope
|
| 26 |
+
|
| 27 |
+
The Diffusers community will apply the following ethical guidelines to the project’s development and help coordinate how the community will integrate the contributions, especially concerning sensitive topics related to ethical concerns.
|
| 28 |
+
|
| 29 |
+
|
| 30 |
+
## Ethical guidelines
|
| 31 |
+
|
| 32 |
+
The following ethical guidelines apply generally, but we will primarily implement them when dealing with ethically sensitive issues while making a technical choice. Furthermore, we commit to adapting those ethical principles over time following emerging harms related to the state of the art of the technology in question.
|
| 33 |
+
|
| 34 |
+
- **Transparency**: we are committed to being transparent in managing PRs, explaining our choices to users, and making technical decisions.
|
| 35 |
+
|
| 36 |
+
- **Consistency**: we are committed to guaranteeing our users the same level of attention in project management, keeping it technically stable and consistent.
|
| 37 |
+
|
| 38 |
+
- **Simplicity**: with a desire to make it easy to use and exploit the Diffusers library, we are committed to keeping the project’s goals lean and coherent.
|
| 39 |
+
|
| 40 |
+
- **Accessibility**: the Diffusers project helps lower the entry bar for contributors who can help run it even without technical expertise. Doing so makes research artifacts more accessible to the community.
|
| 41 |
+
|
| 42 |
+
- **Reproducibility**: we aim to be transparent about the reproducibility of upstream code, models, and datasets when made available through the Diffusers library.
|
| 43 |
+
|
| 44 |
+
- **Responsibility**: as a community and through teamwork, we hold a collective responsibility to our users by anticipating and mitigating this technology's potential risks and dangers.
|
| 45 |
+
|
| 46 |
+
|
| 47 |
+
## Examples of implementations: Safety features and Mechanisms
|
| 48 |
+
|
| 49 |
+
The team works daily to make the technical and non-technical tools available to deal with the potential ethical and social risks associated with diffusion technology. Moreover, the community's input is invaluable in ensuring these features' implementation and raising awareness with us.
|
| 50 |
+
|
| 51 |
+
- [**Community tab**](https://huggingface.co/docs/hub/repositories-pull-requests-discussions): it enables the community to discuss and better collaborate on a project.
|
| 52 |
+
|
| 53 |
+
- **Bias exploration and evaluation**: the Hugging Face team provides a [space](https://huggingface.co/spaces/society-ethics/DiffusionBiasExplorer) to demonstrate the biases in Stable Diffusion interactively. In this sense, we support and encourage bias explorers and evaluations.
|
| 54 |
+
|
| 55 |
+
- **Encouraging safety in deployment**
|
| 56 |
+
|
| 57 |
+
- [**Safe Stable Diffusion**](https://huggingface.co/docs/diffusers/main/en/api/pipelines/stable_diffusion/stable_diffusion_safe): It mitigates the well-known issue that models, like Stable Diffusion, that are trained on unfiltered, web-crawled datasets tend to suffer from inappropriate degeneration. Related paper: [Safe Latent Diffusion: Mitigating Inappropriate Degeneration in Diffusion Models](https://huggingface.co/papers/2211.05105).
|
| 58 |
+
|
| 59 |
+
- [**Safety Checker**](https://github.com/huggingface/diffusers/blob/main/src/diffusers/pipelines/stable_diffusion/safety_checker.py): It checks and compares the class probability of a set of hard-coded harmful concepts in the embedding space against an image after it has been generated. The harmful concepts are intentionally hidden to prevent reverse engineering of the checker.
|
| 60 |
+
|
| 61 |
+
- **Staged released on the Hub**: in particularly sensitive situations, access to some repositories should be restricted. This staged release is an intermediary step that allows the repository’s authors to have more control over its use.
|
| 62 |
+
|
| 63 |
+
- **Licensing**: [OpenRAILs](https://huggingface.co/blog/open_rail), a new type of licensing, allow us to ensure free access while having a set of restrictions that ensure more responsible use.
|
tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/conceptual/evaluation.md
ADDED
|
@@ -0,0 +1,566 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Evaluating Diffusion Models
|
| 14 |
+
|
| 15 |
+
<a target="_blank" href="https://colab.research.google.com/github/huggingface/notebooks/blob/main/diffusers/evaluation.ipynb">
|
| 16 |
+
<img src="https://colab.research.google.com/assets/colab-badge.svg" alt="Open In Colab"/>
|
| 17 |
+
</a>
|
| 18 |
+
|
| 19 |
+
> [!TIP]
|
| 20 |
+
> This document has now grown outdated given the emergence of existing evaluation frameworks for diffusion models for image generation. Please check
|
| 21 |
+
> out works like [HEIM](https://crfm.stanford.edu/helm/heim/latest/), [T2I-Compbench](https://huggingface.co/papers/2307.06350),
|
| 22 |
+
> [GenEval](https://huggingface.co/papers/2310.11513).
|
| 23 |
+
|
| 24 |
+
Evaluation of generative models like [Stable Diffusion](https://huggingface.co/docs/diffusers/stable_diffusion) is subjective in nature. But as practitioners and researchers, we often have to make careful choices amongst many different possibilities. So, when working with different generative models (like GANs, Diffusion, etc.), how do we choose one over the other?
|
| 25 |
+
|
| 26 |
+
Qualitative evaluation of such models can be error-prone and might incorrectly influence a decision.
|
| 27 |
+
However, quantitative metrics don't necessarily correspond to image quality. So, usually, a combination
|
| 28 |
+
of both qualitative and quantitative evaluations provides a stronger signal when choosing one model
|
| 29 |
+
over the other.
|
| 30 |
+
|
| 31 |
+
In this document, we provide a non-exhaustive overview of qualitative and quantitative methods to evaluate Diffusion models. For quantitative methods, we specifically focus on how to implement them alongside `diffusers`.
|
| 32 |
+
|
| 33 |
+
The methods shown in this document can also be used to evaluate different [noise schedulers](https://huggingface.co/docs/diffusers/main/en/api/schedulers/overview) keeping the underlying generation model fixed.
|
| 34 |
+
|
| 35 |
+
## Scenarios
|
| 36 |
+
|
| 37 |
+
We cover Diffusion models with the following pipelines:
|
| 38 |
+
|
| 39 |
+
- Text-guided image generation (such as the [`StableDiffusionPipeline`](https://huggingface.co/docs/diffusers/main/en/api/pipelines/stable_diffusion/text2img)).
|
| 40 |
+
- Text-guided image generation, additionally conditioned on an input image (such as the [`StableDiffusionImg2ImgPipeline`](https://huggingface.co/docs/diffusers/main/en/api/pipelines/stable_diffusion/img2img) and [`StableDiffusionInstructPix2PixPipeline`](https://huggingface.co/docs/diffusers/main/en/api/pipelines/pix2pix)).
|
| 41 |
+
- Class-conditioned image generation models (such as the [`DiTPipeline`](https://huggingface.co/docs/diffusers/main/en/api/pipelines/dit)).
|
| 42 |
+
|
| 43 |
+
## Qualitative Evaluation
|
| 44 |
+
|
| 45 |
+
Qualitative evaluation typically involves human assessment of generated images. Quality is measured across aspects such as compositionality, image-text alignment, and spatial relations. Common prompts provide a degree of uniformity for subjective metrics.
|
| 46 |
+
DrawBench and PartiPrompts are prompt datasets used for qualitative benchmarking. DrawBench and PartiPrompts were introduced by [Imagen](https://imagen.research.google/) and [Parti](https://parti.research.google/) respectively.
|
| 47 |
+
|
| 48 |
+
From the [official Parti website](https://parti.research.google/):
|
| 49 |
+
|
| 50 |
+
> PartiPrompts (P2) is a rich set of over 1600 prompts in English that we release as part of this work. P2 can be used to measure model capabilities across various categories and challenge aspects.
|
| 51 |
+
|
| 52 |
+
|
| 53 |
+
|
| 54 |
+
PartiPrompts has the following columns:
|
| 55 |
+
|
| 56 |
+
- Prompt
|
| 57 |
+
- Category of the prompt (such as “Abstract”, “World Knowledge”, etc.)
|
| 58 |
+
- Challenge reflecting the difficulty (such as “Basic”, “Complex”, “Writing & Symbols”, etc.)
|
| 59 |
+
|
| 60 |
+
These benchmarks allow for side-by-side human evaluation of different image generation models.
|
| 61 |
+
|
| 62 |
+
For this, the 🧨 Diffusers team has built **Open Parti Prompts**, which is a community-driven qualitative benchmark based on Parti Prompts to compare state-of-the-art open-source diffusion models:
|
| 63 |
+
- [Open Parti Prompts Game](https://huggingface.co/spaces/OpenGenAI/open-parti-prompts): For 10 parti prompts, 4 generated images are shown and the user selects the image that suits the prompt best.
|
| 64 |
+
- [Open Parti Prompts Leaderboard](https://huggingface.co/spaces/OpenGenAI/parti-prompts-leaderboard): The leaderboard comparing the currently best open-sourced diffusion models to each other.
|
| 65 |
+
|
| 66 |
+
To manually compare images, let’s see how we can use `diffusers` on a couple of PartiPrompts.
|
| 67 |
+
|
| 68 |
+
Below we show some prompts sampled across different challenges: Basic, Complex, Linguistic Structures, Imagination, and Writing & Symbols. Here we are using PartiPrompts as a [dataset](https://huggingface.co/datasets/nateraw/parti-prompts).
|
| 69 |
+
|
| 70 |
+
```python
|
| 71 |
+
from datasets import load_dataset
|
| 72 |
+
|
| 73 |
+
# prompts = load_dataset("nateraw/parti-prompts", split="train")
|
| 74 |
+
# prompts = prompts.shuffle()
|
| 75 |
+
# sample_prompts = [prompts[i]["Prompt"] for i in range(5)]
|
| 76 |
+
|
| 77 |
+
# Fixing these sample prompts in the interest of reproducibility.
|
| 78 |
+
sample_prompts = [
|
| 79 |
+
"a corgi",
|
| 80 |
+
"a hot air balloon with a yin-yang symbol, with the moon visible in the daytime sky",
|
| 81 |
+
"a car with no windows",
|
| 82 |
+
"a cube made of porcupine",
|
| 83 |
+
'The saying "BE EXCELLENT TO EACH OTHER" written on a red brick wall with a graffiti image of a green alien wearing a tuxedo. A yellow fire hydrant is on a sidewalk in the foreground.',
|
| 84 |
+
]
|
| 85 |
+
```
|
| 86 |
+
|
| 87 |
+
Now we can use these prompts to generate some images using Stable Diffusion ([v1-4 checkpoint](https://huggingface.co/CompVis/stable-diffusion-v1-4)):
|
| 88 |
+
|
| 89 |
+
```python
|
| 90 |
+
import torch
|
| 91 |
+
|
| 92 |
+
seed = 0
|
| 93 |
+
generator = torch.manual_seed(seed)
|
| 94 |
+
|
| 95 |
+
images = sd_pipeline(sample_prompts, num_images_per_prompt=1, generator=generator).images
|
| 96 |
+
```
|
| 97 |
+
|
| 98 |
+
|
| 99 |
+
|
| 100 |
+
We can also set `num_images_per_prompt` accordingly to compare different images for the same prompt. Running the same pipeline but with a different checkpoint ([v1-5](https://huggingface.co/stable-diffusion-v1-5/stable-diffusion-v1-5)), yields:
|
| 101 |
+
|
| 102 |
+
|
| 103 |
+
|
| 104 |
+
Once several images are generated from all the prompts using multiple models (under evaluation), these results are presented to human evaluators for scoring. For
|
| 105 |
+
more details on the DrawBench and PartiPrompts benchmarks, refer to their respective papers.
|
| 106 |
+
|
| 107 |
+
> [!TIP]
|
| 108 |
+
> It is useful to look at some inference samples while a model is training to measure the
|
| 109 |
+
> training progress. In our [training scripts](https://github.com/huggingface/diffusers/tree/main/examples/), we support this utility with additional support for
|
| 110 |
+
> logging to TensorBoard and Weights & Biases.
|
| 111 |
+
|
| 112 |
+
## Quantitative Evaluation
|
| 113 |
+
|
| 114 |
+
In this section, we will walk you through how to evaluate three different diffusion pipelines using:
|
| 115 |
+
|
| 116 |
+
- CLIP score
|
| 117 |
+
- CLIP directional similarity
|
| 118 |
+
- FID
|
| 119 |
+
|
| 120 |
+
### Text-guided image generation
|
| 121 |
+
|
| 122 |
+
[CLIP score](https://huggingface.co/papers/2104.08718) measures the compatibility of image-caption pairs. Higher CLIP scores imply higher compatibility 🔼. The CLIP score is a quantitative measurement of the qualitative concept "compatibility". Image-caption pair compatibility can also be thought of as the semantic similarity between the image and the caption. CLIP score was found to have high correlation with human judgement.
|
| 123 |
+
|
| 124 |
+
Let's first load a [`StableDiffusionPipeline`]:
|
| 125 |
+
|
| 126 |
+
```python
|
| 127 |
+
from diffusers import StableDiffusionPipeline
|
| 128 |
+
import torch
|
| 129 |
+
|
| 130 |
+
model_ckpt = "CompVis/stable-diffusion-v1-4"
|
| 131 |
+
sd_pipeline = StableDiffusionPipeline.from_pretrained(model_ckpt, torch_dtype=torch.float16).to("cuda")
|
| 132 |
+
```
|
| 133 |
+
|
| 134 |
+
Generate some images with multiple prompts:
|
| 135 |
+
|
| 136 |
+
```python
|
| 137 |
+
prompts = [
|
| 138 |
+
"a photo of an astronaut riding a horse on mars",
|
| 139 |
+
"A high tech solarpunk utopia in the Amazon rainforest",
|
| 140 |
+
"A pikachu fine dining with a view to the Eiffel Tower",
|
| 141 |
+
"A mecha robot in a favela in expressionist style",
|
| 142 |
+
"an insect robot preparing a delicious meal",
|
| 143 |
+
"A small cabin on top of a snowy mountain in the style of Disney, artstation",
|
| 144 |
+
]
|
| 145 |
+
|
| 146 |
+
images = sd_pipeline(prompts, num_images_per_prompt=1, output_type="np").images
|
| 147 |
+
|
| 148 |
+
print(images.shape)
|
| 149 |
+
# (6, 512, 512, 3)
|
| 150 |
+
```
|
| 151 |
+
|
| 152 |
+
And then, we calculate the CLIP score.
|
| 153 |
+
|
| 154 |
+
```python
|
| 155 |
+
from torchmetrics.functional.multimodal import clip_score
|
| 156 |
+
from functools import partial
|
| 157 |
+
|
| 158 |
+
clip_score_fn = partial(clip_score, model_name_or_path="openai/clip-vit-base-patch16")
|
| 159 |
+
|
| 160 |
+
def calculate_clip_score(images, prompts):
|
| 161 |
+
images_int = (images * 255).astype("uint8")
|
| 162 |
+
clip_score = clip_score_fn(torch.from_numpy(images_int).permute(0, 3, 1, 2), prompts).detach()
|
| 163 |
+
return round(float(clip_score), 4)
|
| 164 |
+
|
| 165 |
+
sd_clip_score = calculate_clip_score(images, prompts)
|
| 166 |
+
print(f"CLIP score: {sd_clip_score}")
|
| 167 |
+
# CLIP score: 35.7038
|
| 168 |
+
```
|
| 169 |
+
|
| 170 |
+
In the above example, we generated one image per prompt. If we generated multiple images per prompt, we would have to take the average score from the generated images per prompt.
|
| 171 |
+
|
| 172 |
+
Now, if we wanted to compare two checkpoints compatible with the [`StableDiffusionPipeline`] we should pass a generator while calling the pipeline. First, we generate images with a
|
| 173 |
+
fixed seed with the [v1-4 Stable Diffusion checkpoint](https://huggingface.co/CompVis/stable-diffusion-v1-4):
|
| 174 |
+
|
| 175 |
+
```python
|
| 176 |
+
seed = 0
|
| 177 |
+
generator = torch.manual_seed(seed)
|
| 178 |
+
|
| 179 |
+
images = sd_pipeline(prompts, num_images_per_prompt=1, generator=generator, output_type="np").images
|
| 180 |
+
```
|
| 181 |
+
|
| 182 |
+
Then we load the [v1-5 checkpoint](https://huggingface.co/stable-diffusion-v1-5/stable-diffusion-v1-5) to generate images:
|
| 183 |
+
|
| 184 |
+
```python
|
| 185 |
+
model_ckpt_1_5 = "stable-diffusion-v1-5/stable-diffusion-v1-5"
|
| 186 |
+
sd_pipeline_1_5 = StableDiffusionPipeline.from_pretrained(model_ckpt_1_5, torch_dtype=torch.float16).to("cuda")
|
| 187 |
+
|
| 188 |
+
images_1_5 = sd_pipeline_1_5(prompts, num_images_per_prompt=1, generator=generator, output_type="np").images
|
| 189 |
+
```
|
| 190 |
+
|
| 191 |
+
And finally, we compare their CLIP scores:
|
| 192 |
+
|
| 193 |
+
```python
|
| 194 |
+
sd_clip_score_1_4 = calculate_clip_score(images, prompts)
|
| 195 |
+
print(f"CLIP Score with v-1-4: {sd_clip_score_1_4}")
|
| 196 |
+
# CLIP Score with v-1-4: 34.9102
|
| 197 |
+
|
| 198 |
+
sd_clip_score_1_5 = calculate_clip_score(images_1_5, prompts)
|
| 199 |
+
print(f"CLIP Score with v-1-5: {sd_clip_score_1_5}")
|
| 200 |
+
# CLIP Score with v-1-5: 36.2137
|
| 201 |
+
```
|
| 202 |
+
|
| 203 |
+
It seems like the [v1-5](https://huggingface.co/stable-diffusion-v1-5/stable-diffusion-v1-5) checkpoint performs better than its predecessor. Note, however, that the number of prompts we used to compute the CLIP scores is quite low. For a more practical evaluation, this number should be way higher, and the prompts should be diverse.
|
| 204 |
+
|
| 205 |
+
> [!WARNING]
|
| 206 |
+
> By construction, there are some limitations in this score. The captions in the training dataset
|
| 207 |
+
> were crawled from the web and extracted from `alt` and similar tags associated an image on the internet.
|
| 208 |
+
> They are not necessarily representative of what a human being would use to describe an image. Hence we
|
| 209 |
+
> had to "engineer" some prompts here.
|
| 210 |
+
|
| 211 |
+
### Image-conditioned text-to-image generation
|
| 212 |
+
|
| 213 |
+
In this case, we condition the generation pipeline with an input image as well as a text prompt. Let's take the [`StableDiffusionInstructPix2PixPipeline`], as an example. It takes an edit instruction as an input prompt and an input image to be edited.
|
| 214 |
+
|
| 215 |
+
Here is one example:
|
| 216 |
+
|
| 217 |
+
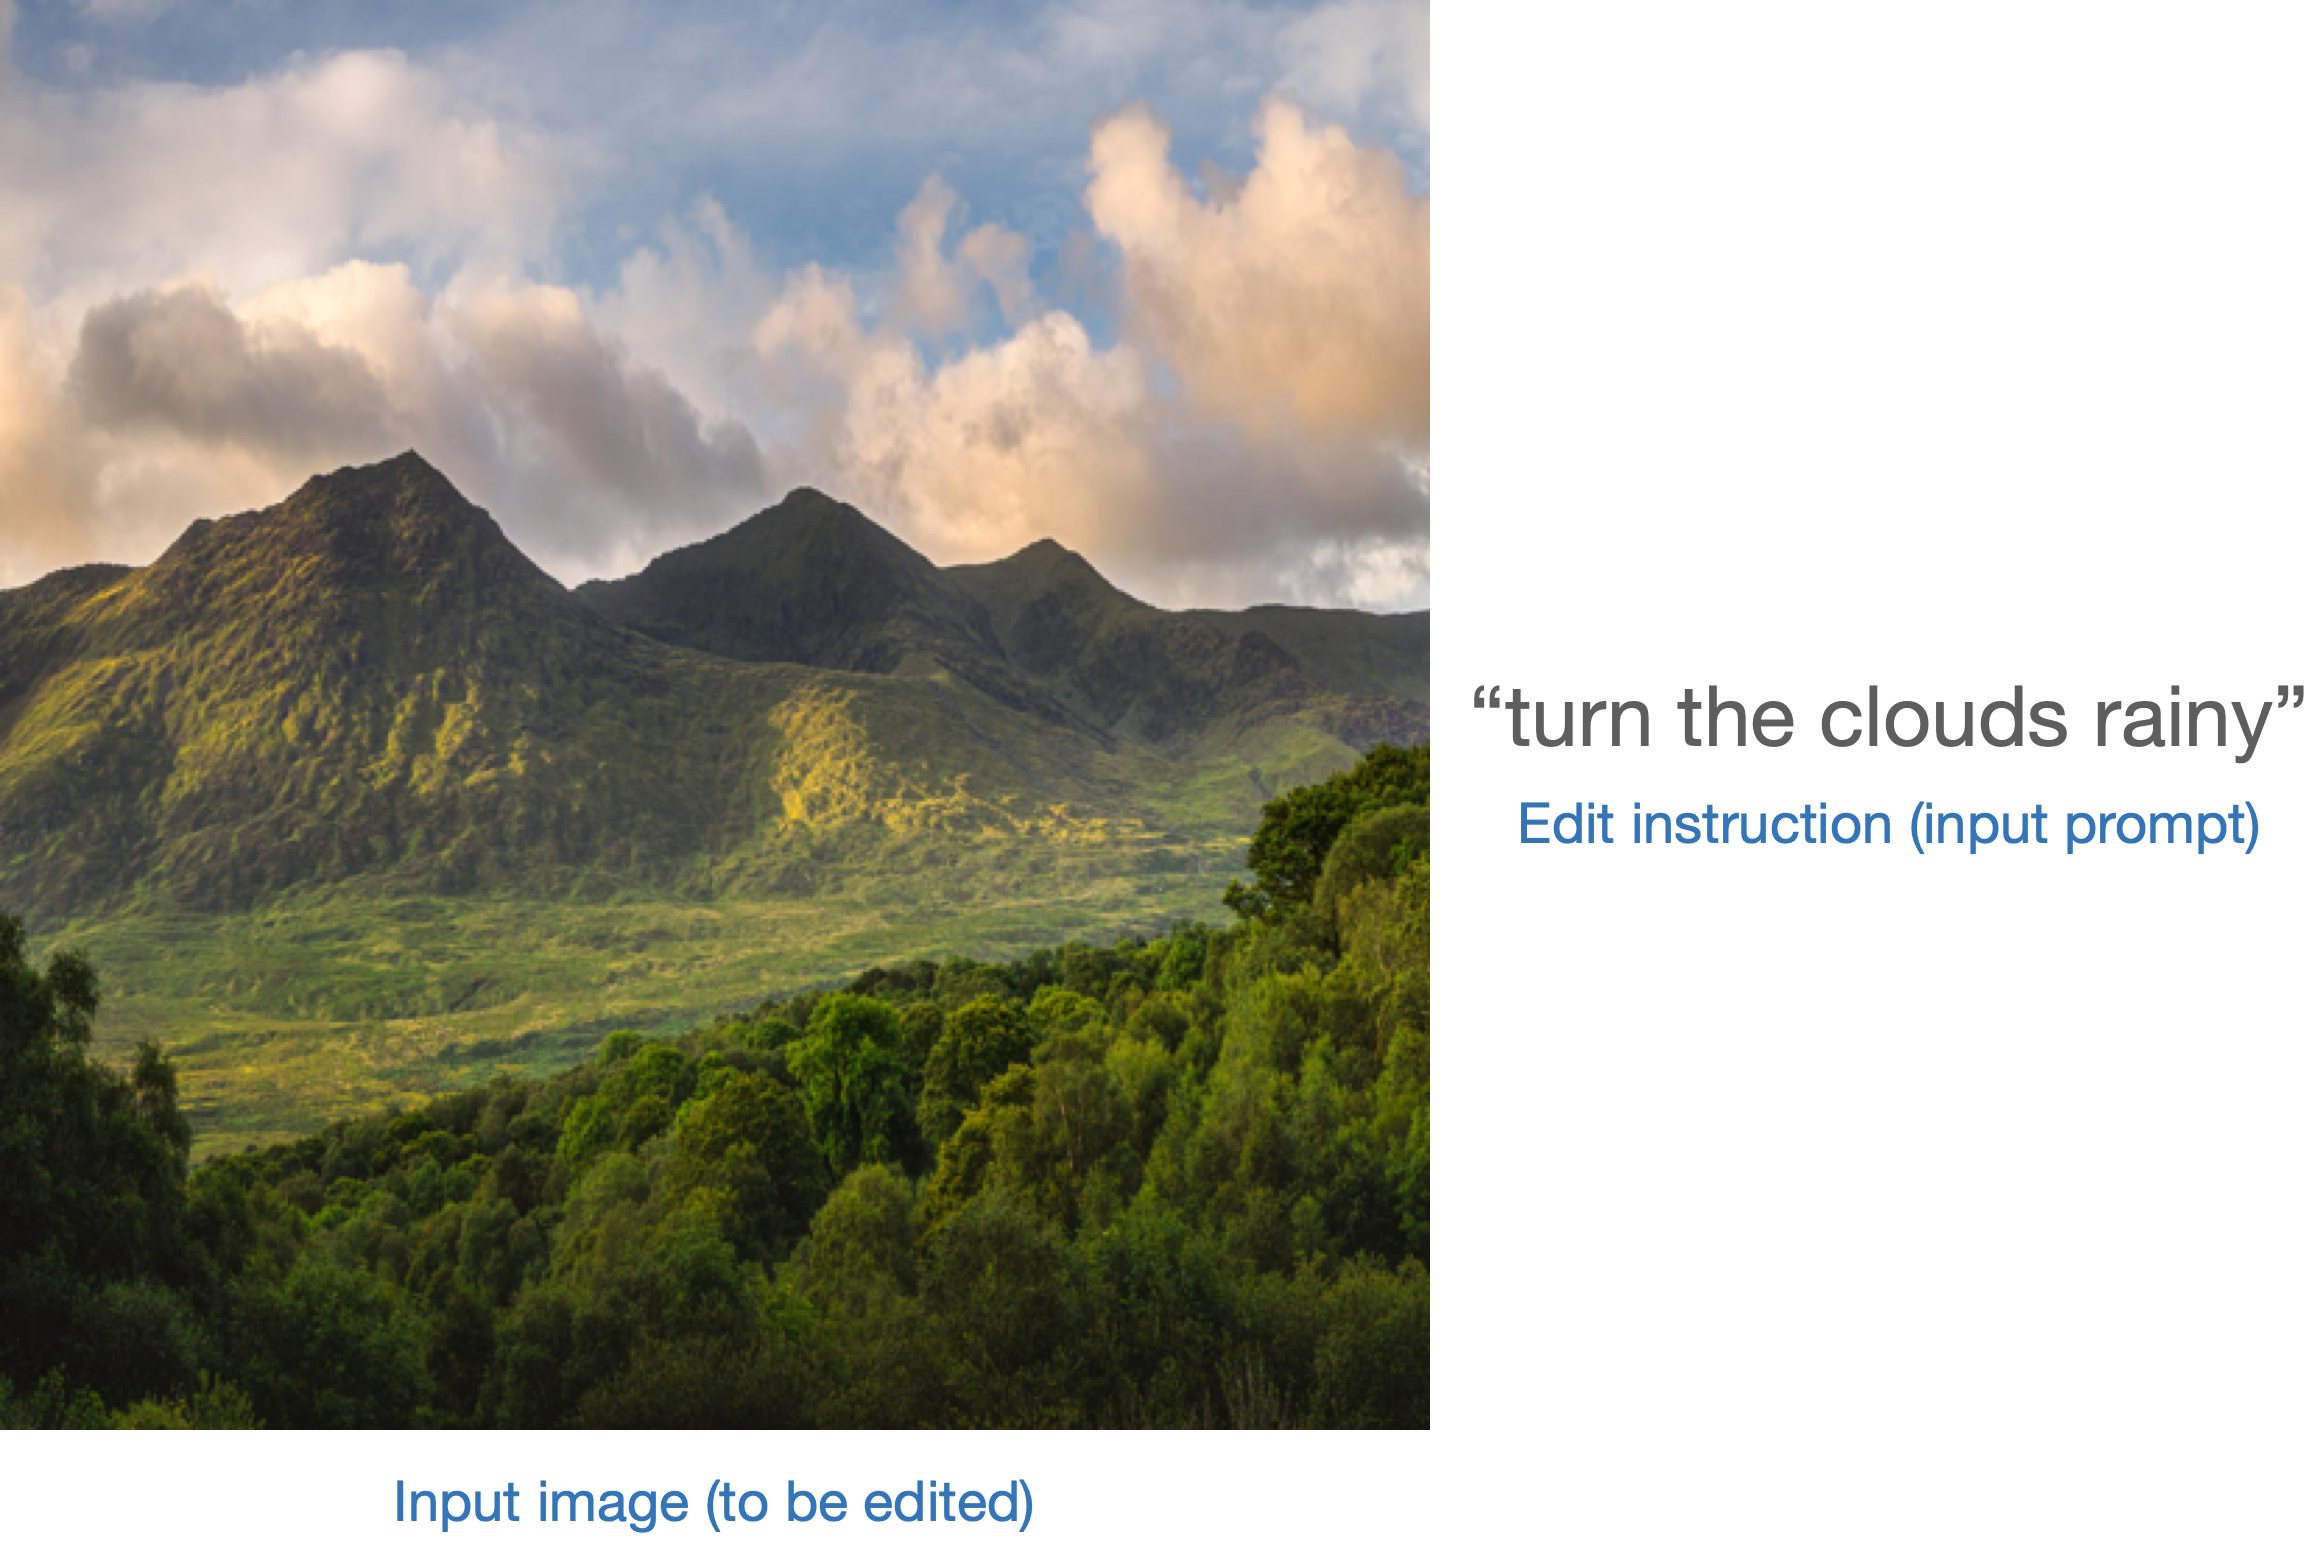
|
| 218 |
+
|
| 219 |
+
One strategy to evaluate such a model is to measure the consistency of the change between the two images (in [CLIP](https://huggingface.co/docs/transformers/model_doc/clip) space) with the change between the two image captions (as shown in [CLIP-Guided Domain Adaptation of Image Generators](https://huggingface.co/papers/2108.00946)). This is referred to as the "**CLIP directional similarity**".
|
| 220 |
+
|
| 221 |
+
- Caption 1 corresponds to the input image (image 1) that is to be edited.
|
| 222 |
+
- Caption 2 corresponds to the edited image (image 2). It should reflect the edit instruction.
|
| 223 |
+
|
| 224 |
+
Following is a pictorial overview:
|
| 225 |
+
|
| 226 |
+
|
| 227 |
+
|
| 228 |
+
We have prepared a mini dataset to implement this metric. Let's first load the dataset.
|
| 229 |
+
|
| 230 |
+
```python
|
| 231 |
+
from datasets import load_dataset
|
| 232 |
+
|
| 233 |
+
dataset = load_dataset("sayakpaul/instructpix2pix-demo", split="train")
|
| 234 |
+
dataset.features
|
| 235 |
+
```
|
| 236 |
+
|
| 237 |
+
```bash
|
| 238 |
+
{'input': Value(dtype='string', id=None),
|
| 239 |
+
'edit': Value(dtype='string', id=None),
|
| 240 |
+
'output': Value(dtype='string', id=None),
|
| 241 |
+
'image': Image(decode=True, id=None)}
|
| 242 |
+
```
|
| 243 |
+
|
| 244 |
+
Here we have:
|
| 245 |
+
|
| 246 |
+
- `input` is a caption corresponding to the `image`.
|
| 247 |
+
- `edit` denotes the edit instruction.
|
| 248 |
+
- `output` denotes the modified caption reflecting the `edit` instruction.
|
| 249 |
+
|
| 250 |
+
Let's take a look at a sample.
|
| 251 |
+
|
| 252 |
+
```python
|
| 253 |
+
idx = 0
|
| 254 |
+
print(f"Original caption: {dataset[idx]['input']}")
|
| 255 |
+
print(f"Edit instruction: {dataset[idx]['edit']}")
|
| 256 |
+
print(f"Modified caption: {dataset[idx]['output']}")
|
| 257 |
+
```
|
| 258 |
+
|
| 259 |
+
```bash
|
| 260 |
+
Original caption: 2. FAROE ISLANDS: An archipelago of 18 mountainous isles in the North Atlantic Ocean between Norway and Iceland, the Faroe Islands has 'everything you could hope for', according to Big 7 Travel. It boasts 'crystal clear waterfalls, rocky cliffs that seem to jut out of nowhere and velvety green hills'
|
| 261 |
+
Edit instruction: make the isles all white marble
|
| 262 |
+
Modified caption: 2. WHITE MARBLE ISLANDS: An archipelago of 18 mountainous white marble isles in the North Atlantic Ocean between Norway and Iceland, the White Marble Islands has 'everything you could hope for', according to Big 7 Travel. It boasts 'crystal clear waterfalls, rocky cliffs that seem to jut out of nowhere and velvety green hills'
|
| 263 |
+
```
|
| 264 |
+
|
| 265 |
+
And here is the image:
|
| 266 |
+
|
| 267 |
+
```python
|
| 268 |
+
dataset[idx]["image"]
|
| 269 |
+
```
|
| 270 |
+
|
| 271 |
+
|
| 272 |
+
|
| 273 |
+
We will first edit the images of our dataset with the edit instruction and compute the directional similarity.
|
| 274 |
+
|
| 275 |
+
Let's first load the [`StableDiffusionInstructPix2PixPipeline`]:
|
| 276 |
+
|
| 277 |
+
```python
|
| 278 |
+
from diffusers import StableDiffusionInstructPix2PixPipeline
|
| 279 |
+
|
| 280 |
+
instruct_pix2pix_pipeline = StableDiffusionInstructPix2PixPipeline.from_pretrained(
|
| 281 |
+
"timbrooks/instruct-pix2pix", torch_dtype=torch.float16
|
| 282 |
+
).to("cuda")
|
| 283 |
+
```
|
| 284 |
+
|
| 285 |
+
Now, we perform the edits:
|
| 286 |
+
|
| 287 |
+
```python
|
| 288 |
+
import numpy as np
|
| 289 |
+
|
| 290 |
+
|
| 291 |
+
def edit_image(input_image, instruction):
|
| 292 |
+
image = instruct_pix2pix_pipeline(
|
| 293 |
+
instruction,
|
| 294 |
+
image=input_image,
|
| 295 |
+
output_type="np",
|
| 296 |
+
generator=generator,
|
| 297 |
+
).images[0]
|
| 298 |
+
return image
|
| 299 |
+
|
| 300 |
+
input_images = []
|
| 301 |
+
original_captions = []
|
| 302 |
+
modified_captions = []
|
| 303 |
+
edited_images = []
|
| 304 |
+
|
| 305 |
+
for idx in range(len(dataset)):
|
| 306 |
+
input_image = dataset[idx]["image"]
|
| 307 |
+
edit_instruction = dataset[idx]["edit"]
|
| 308 |
+
edited_image = edit_image(input_image, edit_instruction)
|
| 309 |
+
|
| 310 |
+
input_images.append(np.array(input_image))
|
| 311 |
+
original_captions.append(dataset[idx]["input"])
|
| 312 |
+
modified_captions.append(dataset[idx]["output"])
|
| 313 |
+
edited_images.append(edited_image)
|
| 314 |
+
```
|
| 315 |
+
|
| 316 |
+
To measure the directional similarity, we first load CLIP's image and text encoders:
|
| 317 |
+
|
| 318 |
+
```python
|
| 319 |
+
from transformers import (
|
| 320 |
+
CLIPTokenizer,
|
| 321 |
+
CLIPTextModelWithProjection,
|
| 322 |
+
CLIPVisionModelWithProjection,
|
| 323 |
+
CLIPImageProcessor,
|
| 324 |
+
)
|
| 325 |
+
|
| 326 |
+
clip_id = "openai/clip-vit-large-patch14"
|
| 327 |
+
tokenizer = CLIPTokenizer.from_pretrained(clip_id)
|
| 328 |
+
text_encoder = CLIPTextModelWithProjection.from_pretrained(clip_id).to("cuda")
|
| 329 |
+
image_processor = CLIPImageProcessor.from_pretrained(clip_id)
|
| 330 |
+
image_encoder = CLIPVisionModelWithProjection.from_pretrained(clip_id).to("cuda")
|
| 331 |
+
```
|
| 332 |
+
|
| 333 |
+
Notice that we are using a particular CLIP checkpoint, i.e., `openai/clip-vit-large-patch14`. This is because the Stable Diffusion pre-training was performed with this CLIP variant. For more details, refer to the [documentation](https://huggingface.co/docs/transformers/model_doc/clip).
|
| 334 |
+
|
| 335 |
+
Next, we prepare a PyTorch `nn.Module` to compute directional similarity:
|
| 336 |
+
|
| 337 |
+
```python
|
| 338 |
+
import torch.nn as nn
|
| 339 |
+
import torch.nn.functional as F
|
| 340 |
+
|
| 341 |
+
|
| 342 |
+
class DirectionalSimilarity(nn.Module):
|
| 343 |
+
def __init__(self, tokenizer, text_encoder, image_processor, image_encoder):
|
| 344 |
+
super().__init__()
|
| 345 |
+
self.tokenizer = tokenizer
|
| 346 |
+
self.text_encoder = text_encoder
|
| 347 |
+
self.image_processor = image_processor
|
| 348 |
+
self.image_encoder = image_encoder
|
| 349 |
+
|
| 350 |
+
def preprocess_image(self, image):
|
| 351 |
+
image = self.image_processor(image, return_tensors="pt")["pixel_values"]
|
| 352 |
+
return {"pixel_values": image.to("cuda")}
|
| 353 |
+
|
| 354 |
+
def tokenize_text(self, text):
|
| 355 |
+
inputs = self.tokenizer(
|
| 356 |
+
text,
|
| 357 |
+
max_length=self.tokenizer.model_max_length,
|
| 358 |
+
padding="max_length",
|
| 359 |
+
truncation=True,
|
| 360 |
+
return_tensors="pt",
|
| 361 |
+
)
|
| 362 |
+
return {"input_ids": inputs.input_ids.to("cuda")}
|
| 363 |
+
|
| 364 |
+
def encode_image(self, image):
|
| 365 |
+
preprocessed_image = self.preprocess_image(image)
|
| 366 |
+
image_features = self.image_encoder(**preprocessed_image).image_embeds
|
| 367 |
+
image_features = image_features / image_features.norm(dim=1, keepdim=True)
|
| 368 |
+
return image_features
|
| 369 |
+
|
| 370 |
+
def encode_text(self, text):
|
| 371 |
+
tokenized_text = self.tokenize_text(text)
|
| 372 |
+
text_features = self.text_encoder(**tokenized_text).text_embeds
|
| 373 |
+
text_features = text_features / text_features.norm(dim=1, keepdim=True)
|
| 374 |
+
return text_features
|
| 375 |
+
|
| 376 |
+
def compute_directional_similarity(self, img_feat_one, img_feat_two, text_feat_one, text_feat_two):
|
| 377 |
+
sim_direction = F.cosine_similarity(img_feat_two - img_feat_one, text_feat_two - text_feat_one)
|
| 378 |
+
return sim_direction
|
| 379 |
+
|
| 380 |
+
def forward(self, image_one, image_two, caption_one, caption_two):
|
| 381 |
+
img_feat_one = self.encode_image(image_one)
|
| 382 |
+
img_feat_two = self.encode_image(image_two)
|
| 383 |
+
text_feat_one = self.encode_text(caption_one)
|
| 384 |
+
text_feat_two = self.encode_text(caption_two)
|
| 385 |
+
directional_similarity = self.compute_directional_similarity(
|
| 386 |
+
img_feat_one, img_feat_two, text_feat_one, text_feat_two
|
| 387 |
+
)
|
| 388 |
+
return directional_similarity
|
| 389 |
+
```
|
| 390 |
+
|
| 391 |
+
Let's put `DirectionalSimilarity` to use now.
|
| 392 |
+
|
| 393 |
+
```python
|
| 394 |
+
dir_similarity = DirectionalSimilarity(tokenizer, text_encoder, image_processor, image_encoder)
|
| 395 |
+
scores = []
|
| 396 |
+
|
| 397 |
+
for i in range(len(input_images)):
|
| 398 |
+
original_image = input_images[i]
|
| 399 |
+
original_caption = original_captions[i]
|
| 400 |
+
edited_image = edited_images[i]
|
| 401 |
+
modified_caption = modified_captions[i]
|
| 402 |
+
|
| 403 |
+
similarity_score = dir_similarity(original_image, edited_image, original_caption, modified_caption)
|
| 404 |
+
scores.append(float(similarity_score.detach().cpu()))
|
| 405 |
+
|
| 406 |
+
print(f"CLIP directional similarity: {np.mean(scores)}")
|
| 407 |
+
# CLIP directional similarity: 0.0797976553440094
|
| 408 |
+
```
|
| 409 |
+
|
| 410 |
+
Like the CLIP Score, the higher the CLIP directional similarity, the better it is.
|
| 411 |
+
|
| 412 |
+
It should be noted that the `StableDiffusionInstructPix2PixPipeline` exposes two arguments, namely, `image_guidance_scale` and `guidance_scale` that let you control the quality of the final edited image. We encourage you to experiment with these two arguments and see the impact of that on the directional similarity.
|
| 413 |
+
|
| 414 |
+
We can extend the idea of this metric to measure how similar the original image and edited version are. To do that, we can just do `F.cosine_similarity(img_feat_two, img_feat_one)`. For these kinds of edits, we would still want the primary semantics of the images to be preserved as much as possible, i.e., a high similarity score.
|
| 415 |
+
|
| 416 |
+
We can use these metrics for similar pipelines such as the [`StableDiffusionPix2PixZeroPipeline`](https://huggingface.co/docs/diffusers/main/en/api/pipelines/pix2pix_zero#diffusers.StableDiffusionPix2PixZeroPipeline).
|
| 417 |
+
|
| 418 |
+
> [!TIP]
|
| 419 |
+
> Both CLIP score and CLIP direction similarity rely on the CLIP model, which can make the evaluations biased.
|
| 420 |
+
|
| 421 |
+
***Extending metrics like IS, FID (discussed later), or KID can be difficult*** when the model under evaluation was pre-trained on a large image-captioning dataset (such as the [LAION-5B dataset](https://laion.ai/blog/laion-5b/)). This is because underlying these metrics is an InceptionNet (pre-trained on the ImageNet-1k dataset) used for extracting intermediate image features. The pre-training dataset of Stable Diffusion may have limited overlap with the pre-training dataset of InceptionNet, so it is not a good candidate here for feature extraction.
|
| 422 |
+
|
| 423 |
+
***Using the above metrics helps evaluate models that are class-conditioned. For example, [DiT](https://huggingface.co/docs/diffusers/main/en/api/pipelines/dit). It was pre-trained being conditioned on the ImageNet-1k classes.***
|
| 424 |
+
|
| 425 |
+
### Class-conditioned image generation
|
| 426 |
+
|
| 427 |
+
Class-conditioned generative models are usually pre-trained on a class-labeled dataset such as [ImageNet-1k](https://huggingface.co/datasets/imagenet-1k). Popular metrics for evaluating these models include Fréchet Inception Distance (FID), Kernel Inception Distance (KID), and Inception Score (IS). In this document, we focus on FID ([Heusel et al.](https://huggingface.co/papers/1706.08500)). We show how to compute it with the [`DiTPipeline`](https://huggingface.co/docs/diffusers/api/pipelines/dit), which uses the [DiT model](https://huggingface.co/papers/2212.09748) under the hood.
|
| 428 |
+
|
| 429 |
+
FID aims to measure how similar are two datasets of images. As per [this resource](https://mmgeneration.readthedocs.io/en/latest/quick_run.html#fid):
|
| 430 |
+
|
| 431 |
+
> Fréchet Inception Distance is a measure of similarity between two datasets of images. It was shown to correlate well with the human judgment of visual quality and is most often used to evaluate the quality of samples of Generative Adversarial Networks. FID is calculated by computing the Fréchet distance between two Gaussians fitted to feature representations of the Inception network.
|
| 432 |
+
|
| 433 |
+
These two datasets are essentially the dataset of real images and the dataset of fake images (generated images in our case). FID is usually calculated with two large datasets. However, for this document, we will work with two mini datasets.
|
| 434 |
+
|
| 435 |
+
Let's first download a few images from the ImageNet-1k training set:
|
| 436 |
+
|
| 437 |
+
```python
|
| 438 |
+
from zipfile import ZipFile
|
| 439 |
+
import requests
|
| 440 |
+
|
| 441 |
+
|
| 442 |
+
def download(url, local_filepath):
|
| 443 |
+
r = requests.get(url)
|
| 444 |
+
with open(local_filepath, "wb") as f:
|
| 445 |
+
f.write(r.content)
|
| 446 |
+
return local_filepath
|
| 447 |
+
|
| 448 |
+
dummy_dataset_url = "https://hf.co/datasets/sayakpaul/sample-datasets/resolve/main/sample-imagenet-images.zip"
|
| 449 |
+
local_filepath = download(dummy_dataset_url, dummy_dataset_url.split("/")[-1])
|
| 450 |
+
|
| 451 |
+
with ZipFile(local_filepath, "r") as zipper:
|
| 452 |
+
zipper.extractall(".")
|
| 453 |
+
```
|
| 454 |
+
|
| 455 |
+
```python
|
| 456 |
+
from PIL import Image
|
| 457 |
+
import os
|
| 458 |
+
import numpy as np
|
| 459 |
+
|
| 460 |
+
dataset_path = "sample-imagenet-images"
|
| 461 |
+
image_paths = sorted([os.path.join(dataset_path, x) for x in os.listdir(dataset_path)])
|
| 462 |
+
|
| 463 |
+
real_images = [np.array(Image.open(path).convert("RGB")) for path in image_paths]
|
| 464 |
+
```
|
| 465 |
+
|
| 466 |
+
These are 10 images from the following ImageNet-1k classes: "cassette_player", "chain_saw" (x2), "church", "gas_pump" (x3), "parachute" (x2), and "tench".
|
| 467 |
+
|
| 468 |
+
<p align="center">
|
| 469 |
+
<img src="https://huggingface.co/datasets/diffusers/docs-images/resolve/main/evaluation_diffusion_models/real-images.png" alt="real-images"><br>
|
| 470 |
+
<em>Real images.</em>
|
| 471 |
+
</p>
|
| 472 |
+
|
| 473 |
+
Now that the images are loaded, let's apply some lightweight pre-processing on them to use them for FID calculation.
|
| 474 |
+
|
| 475 |
+
```python
|
| 476 |
+
from torchvision.transforms import functional as F
|
| 477 |
+
import torch
|
| 478 |
+
|
| 479 |
+
|
| 480 |
+
def preprocess_image(image):
|
| 481 |
+
image = torch.tensor(image).unsqueeze(0)
|
| 482 |
+
image = image.permute(0, 3, 1, 2) / 255.0
|
| 483 |
+
return F.center_crop(image, (256, 256))
|
| 484 |
+
|
| 485 |
+
real_images = torch.cat([preprocess_image(image) for image in real_images])
|
| 486 |
+
print(real_images.shape)
|
| 487 |
+
# torch.Size([10, 3, 256, 256])
|
| 488 |
+
```
|
| 489 |
+
|
| 490 |
+
We now load the [`DiTPipeline`](https://huggingface.co/docs/diffusers/api/pipelines/dit) to generate images conditioned on the above-mentioned classes.
|
| 491 |
+
|
| 492 |
+
```python
|
| 493 |
+
from diffusers import DiTPipeline, DPMSolverMultistepScheduler
|
| 494 |
+
|
| 495 |
+
dit_pipeline = DiTPipeline.from_pretrained("facebook/DiT-XL-2-256", torch_dtype=torch.float16)
|
| 496 |
+
dit_pipeline.scheduler = DPMSolverMultistepScheduler.from_config(dit_pipeline.scheduler.config)
|
| 497 |
+
dit_pipeline = dit_pipeline.to("cuda")
|
| 498 |
+
|
| 499 |
+
seed = 0
|
| 500 |
+
generator = torch.manual_seed(seed)
|
| 501 |
+
|
| 502 |
+
|
| 503 |
+
words = [
|
| 504 |
+
"cassette player",
|
| 505 |
+
"chainsaw",
|
| 506 |
+
"chainsaw",
|
| 507 |
+
"church",
|
| 508 |
+
"gas pump",
|
| 509 |
+
"gas pump",
|
| 510 |
+
"gas pump",
|
| 511 |
+
"parachute",
|
| 512 |
+
"parachute",
|
| 513 |
+
"tench",
|
| 514 |
+
]
|
| 515 |
+
|
| 516 |
+
class_ids = dit_pipeline.get_label_ids(words)
|
| 517 |
+
output = dit_pipeline(class_labels=class_ids, generator=generator, output_type="np")
|
| 518 |
+
|
| 519 |
+
fake_images = output.images
|
| 520 |
+
fake_images = torch.tensor(fake_images)
|
| 521 |
+
fake_images = fake_images.permute(0, 3, 1, 2)
|
| 522 |
+
print(fake_images.shape)
|
| 523 |
+
# torch.Size([10, 3, 256, 256])
|
| 524 |
+
```
|
| 525 |
+
|
| 526 |
+
Now, we can compute the FID using [`torchmetrics`](https://torchmetrics.readthedocs.io/).
|
| 527 |
+
|
| 528 |
+
```python
|
| 529 |
+
from torchmetrics.image.fid import FrechetInceptionDistance
|
| 530 |
+
|
| 531 |
+
fid = FrechetInceptionDistance(normalize=True)
|
| 532 |
+
fid.update(real_images, real=True)
|
| 533 |
+
fid.update(fake_images, real=False)
|
| 534 |
+
|
| 535 |
+
print(f"FID: {float(fid.compute())}")
|
| 536 |
+
# FID: 177.7147216796875
|
| 537 |
+
```
|
| 538 |
+
|
| 539 |
+
The lower the FID, the better it is. Several things can influence FID here:
|
| 540 |
+
|
| 541 |
+
- Number of images (both real and fake)
|
| 542 |
+
- Randomness induced in the diffusion process
|
| 543 |
+
- Number of inference steps in the diffusion process
|
| 544 |
+
- The scheduler being used in the diffusion process
|
| 545 |
+
|
| 546 |
+
For the last two points, it is, therefore, a good practice to run the evaluation across different seeds and inference steps, and then report an average result.
|
| 547 |
+
|
| 548 |
+
> [!WARNING]
|
| 549 |
+
> FID results tend to be fragile as they depend on a lot of factors:
|
| 550 |
+
>
|
| 551 |
+
> * The specific Inception model used during computation.
|
| 552 |
+
> * The implementation accuracy of the computation.
|
| 553 |
+
> * The image format (not the same if we start from PNGs vs JPGs).
|
| 554 |
+
>
|
| 555 |
+
> Keeping that in mind, FID is often most useful when comparing similar runs, but it is
|
| 556 |
+
> hard to reproduce paper results unless the authors carefully disclose the FID
|
| 557 |
+
> measurement code.
|
| 558 |
+
>
|
| 559 |
+
> These points apply to other related metrics too, such as KID and IS.
|
| 560 |
+
|
| 561 |
+
As a final step, let's visually inspect the `fake_images`.
|
| 562 |
+
|
| 563 |
+
<p align="center">
|
| 564 |
+
<img src="https://huggingface.co/datasets/diffusers/docs-images/resolve/main/evaluation_diffusion_models/fake-images.png" alt="fake-images"><br>
|
| 565 |
+
<em>Fake images.</em>
|
| 566 |
+
</p>
|
tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/conceptual/philosophy.md
ADDED
|
@@ -0,0 +1,110 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Philosophy
|
| 14 |
+
|
| 15 |
+
🧨 Diffusers provides **state-of-the-art** pretrained diffusion models across multiple modalities.
|
| 16 |
+
Its purpose is to serve as a **modular toolbox** for both inference and training.
|
| 17 |
+
|
| 18 |
+
We aim at building a library that stands the test of time and therefore take API design very seriously.
|
| 19 |
+
|
| 20 |
+
In a nutshell, Diffusers is built to be a natural extension of PyTorch. Therefore, most of our design choices are based on [PyTorch's Design Principles](https://pytorch.org/docs/stable/community/design.html#pytorch-design-philosophy). Let's go over the most important ones:
|
| 21 |
+
|
| 22 |
+
## Usability over Performance
|
| 23 |
+
|
| 24 |
+
- While Diffusers has many built-in performance-enhancing features (see [Memory and Speed](https://huggingface.co/docs/diffusers/optimization/fp16)), models are always loaded with the highest precision and lowest optimization. Therefore, by default diffusion pipelines are always instantiated on CPU with float32 precision if not otherwise defined by the user. This ensures usability across different platforms and accelerators and means that no complex installations are required to run the library.
|
| 25 |
+
- Diffusers aims to be a **light-weight** package and therefore has very few required dependencies, but many soft dependencies that can improve performance (such as `accelerate`, `safetensors`, `onnx`, etc...). We strive to keep the library as lightweight as possible so that it can be added without much concern as a dependency on other packages.
|
| 26 |
+
- Diffusers prefers simple, self-explainable code over condensed, magic code. This means that short-hand code syntaxes such as lambda functions, and advanced PyTorch operators are often not desired.
|
| 27 |
+
|
| 28 |
+
## Simple over easy
|
| 29 |
+
|
| 30 |
+
As PyTorch states, **explicit is better than implicit** and **simple is better than complex**. This design philosophy is reflected in multiple parts of the library:
|
| 31 |
+
- We follow PyTorch's API with methods like [`DiffusionPipeline.to`](https://huggingface.co/docs/diffusers/main/en/api/diffusion_pipeline#diffusers.DiffusionPipeline.to) to let the user handle device management.
|
| 32 |
+
- Raising concise error messages is preferred to silently correct erroneous input. Diffusers aims at teaching the user, rather than making the library as easy to use as possible.
|
| 33 |
+
- Complex model vs. scheduler logic is exposed instead of magically handled inside. Schedulers/Samplers are separated from diffusion models with minimal dependencies on each other. This forces the user to write the unrolled denoising loop. However, the separation allows for easier debugging and gives the user more control over adapting the denoising process or switching out diffusion models or schedulers.
|
| 34 |
+
- Separately trained components of the diffusion pipeline, *e.g.* the text encoder, the unet, and the variational autoencoder, each have their own model class. This forces the user to handle the interaction between the different model components, and the serialization format separates the model components into different files. However, this allows for easier debugging and customization. DreamBooth or Textual Inversion training
|
| 35 |
+
is very simple thanks to Diffusers' ability to separate single components of the diffusion pipeline.
|
| 36 |
+
|
| 37 |
+
## Tweakable, contributor-friendly over abstraction
|
| 38 |
+
|
| 39 |
+
For large parts of the library, Diffusers adopts an important design principle of the [Transformers library](https://github.com/huggingface/transformers), which is to prefer copy-pasted code over hasty abstractions. This design principle is very opinionated and stands in stark contrast to popular design principles such as [Don't repeat yourself (DRY)](https://en.wikipedia.org/wiki/Don%27t_repeat_yourself).
|
| 40 |
+
In short, just like Transformers does for modeling files, Diffusers prefers to keep an extremely low level of abstraction and very self-contained code for pipelines and schedulers.
|
| 41 |
+
Functions, long code blocks, and even classes can be copied across multiple files which at first can look like a bad, sloppy design choice that makes the library unmaintainable.
|
| 42 |
+
**However**, this design has proven to be extremely successful for Transformers and makes a lot of sense for community-driven, open-source machine learning libraries because:
|
| 43 |
+
- Machine Learning is an extremely fast-moving field in which paradigms, model architectures, and algorithms are changing rapidly, which therefore makes it very difficult to define long-lasting code abstractions.
|
| 44 |
+
- Machine Learning practitioners like to be able to quickly tweak existing code for ideation and research and therefore prefer self-contained code over one that contains many abstractions.
|
| 45 |
+
- Open-source libraries rely on community contributions and therefore must build a library that is easy to contribute to. The more abstract the code, the more dependencies, the harder to read, and the harder to contribute to. Contributors simply stop contributing to very abstract libraries out of fear of breaking vital functionality. If contributing to a library cannot break other fundamental code, not only is it more inviting for potential new contributors, but it is also easier to review and contribute to multiple parts in parallel.
|
| 46 |
+
|
| 47 |
+
At Hugging Face, we call this design the **single-file policy** which means that almost all of the code of a certain class should be written in a single, self-contained file. To read more about the philosophy, you can have a look
|
| 48 |
+
at [this blog post](https://huggingface.co/blog/transformers-design-philosophy).
|
| 49 |
+
|
| 50 |
+
In Diffusers, we follow this philosophy for both pipelines and schedulers, but only partly for diffusion models. The reason we don't follow this design fully for diffusion models is because almost all diffusion pipelines, such
|
| 51 |
+
as [DDPM](https://huggingface.co/docs/diffusers/api/pipelines/ddpm), [Stable Diffusion](https://huggingface.co/docs/diffusers/api/pipelines/stable_diffusion/overview#stable-diffusion-pipelines), [unCLIP (DALL·E 2)](https://huggingface.co/docs/diffusers/api/pipelines/unclip) and [Imagen](https://imagen.research.google/) all rely on the same diffusion model, the [UNet](https://huggingface.co/docs/diffusers/api/models/unet2d-cond).
|
| 52 |
+
|
| 53 |
+
Great, now you should have generally understood why 🧨 Diffusers is designed the way it is 🤗.
|
| 54 |
+
We try to apply these design principles consistently across the library. Nevertheless, there are some minor exceptions to the philosophy or some unlucky design choices. If you have feedback regarding the design, we would ❤️ to hear it [directly on GitHub](https://github.com/huggingface/diffusers/issues/new?assignees=&labels=&template=feedback.md&title=).
|
| 55 |
+
|
| 56 |
+
## Design Philosophy in Details
|
| 57 |
+
|
| 58 |
+
Now, let's look a bit into the nitty-gritty details of the design philosophy. Diffusers essentially consists of three major classes: [pipelines](https://github.com/huggingface/diffusers/tree/main/src/diffusers/pipelines), [models](https://github.com/huggingface/diffusers/tree/main/src/diffusers/models), and [schedulers](https://github.com/huggingface/diffusers/tree/main/src/diffusers/schedulers).
|
| 59 |
+
Let's walk through more in-detail design decisions for each class.
|
| 60 |
+
|
| 61 |
+
### Pipelines
|
| 62 |
+
|
| 63 |
+
Pipelines are designed to be easy to use (therefore do not follow [*Simple over easy*](#simple-over-easy) 100%), are not feature complete, and should loosely be seen as examples of how to use [models](#models) and [schedulers](#schedulers) for inference.
|
| 64 |
+
|
| 65 |
+
The following design principles are followed:
|
| 66 |
+
- Pipelines follow the single-file policy. All pipelines can be found in individual directories under src/diffusers/pipelines. One pipeline folder corresponds to one diffusion paper/project/release. Multiple pipeline files can be gathered in one pipeline folder, as it’s done for [`src/diffusers/pipelines/stable-diffusion`](https://github.com/huggingface/diffusers/tree/main/src/diffusers/pipelines/stable_diffusion). If pipelines share similar functionality, one can make use of the [# Copied from mechanism](https://github.com/huggingface/diffusers/blob/125d783076e5bd9785beb05367a2d2566843a271/src/diffusers/pipelines/stable_diffusion/pipeline_stable_diffusion_img2img.py#L251).
|
| 67 |
+
- Pipelines all inherit from [`DiffusionPipeline`].
|
| 68 |
+
- Every pipeline consists of different model and scheduler components, that are documented in the [`model_index.json` file](https://huggingface.co/stable-diffusion-v1-5/stable-diffusion-v1-5/blob/main/model_index.json), are accessible under the same name as attributes of the pipeline and can be shared between pipelines with [`DiffusionPipeline.components`](https://huggingface.co/docs/diffusers/main/en/api/diffusion_pipeline#diffusers.DiffusionPipeline.components) function.
|
| 69 |
+
- Every pipeline should be loadable via the [`DiffusionPipeline.from_pretrained`](https://huggingface.co/docs/diffusers/main/en/api/diffusion_pipeline#diffusers.DiffusionPipeline.from_pretrained) function.
|
| 70 |
+
- Pipelines should be used **only** for inference.
|
| 71 |
+
- Pipelines should be very readable, self-explanatory, and easy to tweak.
|
| 72 |
+
- Pipelines should be designed to build on top of each other and be easy to integrate into higher-level APIs.
|
| 73 |
+
- Pipelines are **not** intended to be feature-complete user interfaces. For feature-complete user interfaces one should rather have a look at [InvokeAI](https://github.com/invoke-ai/InvokeAI), [Diffuzers](https://github.com/abhishekkrthakur/diffuzers), and [lama-cleaner](https://github.com/Sanster/lama-cleaner).
|
| 74 |
+
- Every pipeline should have one and only one way to run it via a `__call__` method. The naming of the `__call__` arguments should be shared across all pipelines.
|
| 75 |
+
- Pipelines should be named after the task they are intended to solve.
|
| 76 |
+
- In almost all cases, novel diffusion pipelines shall be implemented in a new pipeline folder/file.
|
| 77 |
+
|
| 78 |
+
### Models
|
| 79 |
+
|
| 80 |
+
Models are designed as configurable toolboxes that are natural extensions of [PyTorch's Module class](https://pytorch.org/docs/stable/generated/torch.nn.Module.html). They only partly follow the **single-file policy**.
|
| 81 |
+
|
| 82 |
+
The following design principles are followed:
|
| 83 |
+
- Models correspond to **a type of model architecture**. *E.g.* the [`UNet2DConditionModel`] class is used for all UNet variations that expect 2D image inputs and are conditioned on some context.
|
| 84 |
+
- All models can be found in [`src/diffusers/models`](https://github.com/huggingface/diffusers/tree/main/src/diffusers/models) and every model architecture shall be defined in its file, e.g. [`unets/unet_2d_condition.py`](https://github.com/huggingface/diffusers/blob/main/src/diffusers/models/unets/unet_2d_condition.py), [`transformers/transformer_2d.py`](https://github.com/huggingface/diffusers/blob/main/src/diffusers/models/transformers/transformer_2d.py), etc...
|
| 85 |
+
- Models **do not** follow the single-file policy and should make use of smaller model building blocks, such as [`attention.py`](https://github.com/huggingface/diffusers/blob/main/src/diffusers/models/attention.py), [`resnet.py`](https://github.com/huggingface/diffusers/blob/main/src/diffusers/models/resnet.py), [`embeddings.py`](https://github.com/huggingface/diffusers/blob/main/src/diffusers/models/embeddings.py), etc... **Note**: This is in stark contrast to Transformers' modeling files and shows that models do not really follow the single-file policy.
|
| 86 |
+
- Models intend to expose complexity, just like PyTorch's `Module` class, and give clear error messages.
|
| 87 |
+
- Models all inherit from `ModelMixin` and `ConfigMixin`.
|
| 88 |
+
- Models can be optimized for performance when it doesn’t demand major code changes, keeps backward compatibility, and gives significant memory or compute gain.
|
| 89 |
+
- Models should by default have the highest precision and lowest performance setting.
|
| 90 |
+
- To integrate new model checkpoints whose general architecture can be classified as an architecture that already exists in Diffusers, the existing model architecture shall be adapted to make it work with the new checkpoint. One should only create a new file if the model architecture is fundamentally different.
|
| 91 |
+
- Models should be designed to be easily extendable to future changes. This can be achieved by limiting public function arguments, configuration arguments, and "foreseeing" future changes, *e.g.* it is usually better to add `string` "...type" arguments that can easily be extended to new future types instead of boolean `is_..._type` arguments. Only the minimum amount of changes shall be made to existing architectures to make a new model checkpoint work.
|
| 92 |
+
- The model design is a difficult trade-off between keeping code readable and concise and supporting many model checkpoints. For most parts of the modeling code, classes shall be adapted for new model checkpoints, while there are some exceptions where it is preferred to add new classes to make sure the code is kept concise and
|
| 93 |
+
readable long-term, such as [UNet blocks](https://github.com/huggingface/diffusers/blob/main/src/diffusers/models/unets/unet_2d_blocks.py) and [Attention processors](https://github.com/huggingface/diffusers/blob/main/src/diffusers/models/attention_processor.py).
|
| 94 |
+
|
| 95 |
+
### Schedulers
|
| 96 |
+
|
| 97 |
+
Schedulers are responsible to guide the denoising process for inference as well as to define a noise schedule for training. They are designed as individual classes with loadable configuration files and strongly follow the **single-file policy**.
|
| 98 |
+
|
| 99 |
+
The following design principles are followed:
|
| 100 |
+
- All schedulers are found in [`src/diffusers/schedulers`](https://github.com/huggingface/diffusers/tree/main/src/diffusers/schedulers).
|
| 101 |
+
- Schedulers are **not** allowed to import from large utils files and shall be kept very self-contained.
|
| 102 |
+
- One scheduler Python file corresponds to one scheduler algorithm (as might be defined in a paper).
|
| 103 |
+
- If schedulers share similar functionalities, we can make use of the `# Copied from` mechanism.
|
| 104 |
+
- Schedulers all inherit from `SchedulerMixin` and `ConfigMixin`.
|
| 105 |
+
- Schedulers can be easily swapped out with the [`ConfigMixin.from_config`](https://huggingface.co/docs/diffusers/main/en/api/configuration#diffusers.ConfigMixin.from_config) method as explained in detail [here](../using-diffusers/schedulers).
|
| 106 |
+
- Every scheduler has to have a `set_num_inference_steps`, and a `step` function. `set_num_inference_steps(...)` has to be called before every denoising process, *i.e.* before `step(...)` is called.
|
| 107 |
+
- Every scheduler exposes the timesteps to be "looped over" via a `timesteps` attribute, which is an array of timesteps the model will be called upon.
|
| 108 |
+
- The `step(...)` function takes a predicted model output and the "current" sample (x_t) and returns the "previous", slightly more denoised sample (x_t-1).
|
| 109 |
+
- Given the complexity of diffusion schedulers, the `step` function does not expose all the complexity and can be a bit of a "black box".
|
| 110 |
+
- In almost all cases, novel schedulers shall be implemented in a new scheduling file.
|
tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/hybrid_inference/api_reference.md
ADDED
|
@@ -0,0 +1,11 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Remote inference
|
| 2 |
+
|
| 3 |
+
Remote inference provides access to an [Inference Endpoint](https://huggingface.co/docs/inference-endpoints/index) to offload local generation requirements for decoding and encoding.
|
| 4 |
+
|
| 5 |
+
## remote_decode
|
| 6 |
+
|
| 7 |
+
[[autodoc]] utils.remote_utils.remote_decode
|
| 8 |
+
|
| 9 |
+
## remote_encode
|
| 10 |
+
|
| 11 |
+
[[autodoc]] utils.remote_utils.remote_encode
|
tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/hybrid_inference/overview.md
ADDED
|
@@ -0,0 +1,305 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Remote inference
|
| 14 |
+
|
| 15 |
+
> [!TIP]
|
| 16 |
+
> This is currently an experimental feature, and if you have any feedback, please feel free to leave it [here](https://github.com/huggingface/diffusers/issues/new?template=remote-vae-pilot-feedback.yml).
|
| 17 |
+
|
| 18 |
+
Remote inference offloads the decoding and encoding process to a remote endpoint to relax the memory requirements for local inference with large models. This feature is powered by [Inference Endpoints](https://huggingface.co/docs/inference-endpoints/index). Refer to the table below for the supported models and endpoint.
|
| 19 |
+
|
| 20 |
+
| Model | Endpoint | Checkpoint | Support |
|
| 21 |
+
|---|---|---|---|
|
| 22 |
+
| Stable Diffusion v1 | https://q1bj3bpq6kzilnsu.us-east-1.aws.endpoints.huggingface.cloud | [stabilityai/sd-vae-ft-mse](https://huggingface.co/stabilityai/sd-vae-ft-mse) | encode/decode |
|
| 23 |
+
| Stable Diffusion XL | https://x2dmsqunjd6k9prw.us-east-1.aws.endpoints.huggingface.cloud | [madebyollin/sdxl-vae-fp16-fix](https://huggingface.co/madebyollin/sdxl-vae-fp16-fix) | encode/decode |
|
| 24 |
+
| Flux | https://whhx50ex1aryqvw6.us-east-1.aws.endpoints.huggingface.cloud | [black-forest-labs/FLUX.1-schnell](https://huggingface.co/black-forest-labs/FLUX.1-schnell) | encode/decode |
|
| 25 |
+
| HunyuanVideo | https://o7ywnmrahorts457.us-east-1.aws.endpoints.huggingface.cloud | [hunyuanvideo-community/HunyuanVideo](https://huggingface.co/hunyuanvideo-community/HunyuanVideo) | decode |
|
| 26 |
+
|
| 27 |
+
This guide will show you how to encode and decode latents with remote inference.
|
| 28 |
+
|
| 29 |
+
## Encoding
|
| 30 |
+
|
| 31 |
+
Encoding converts images and videos into latent representations. Refer to the table below for the supported VAEs.
|
| 32 |
+
|
| 33 |
+
Pass an image to [`~utils.remote_encode`] to encode it. The specific `scaling_factor` and `shift_factor` values for each model can be found in the [Remote inference](../hybrid_inference/api_reference) API reference.
|
| 34 |
+
|
| 35 |
+
```py
|
| 36 |
+
import torch
|
| 37 |
+
from diffusers import FluxPipeline
|
| 38 |
+
from diffusers.utils import load_image
|
| 39 |
+
from diffusers.utils.remote_utils import remote_encode
|
| 40 |
+
|
| 41 |
+
pipeline = FluxPipeline.from_pretrained(
|
| 42 |
+
"black-forest-labs/FLUX.1-schnell",
|
| 43 |
+
torch_dtype=torch.float16,
|
| 44 |
+
vae=None,
|
| 45 |
+
device_map="cuda"
|
| 46 |
+
)
|
| 47 |
+
|
| 48 |
+
init_image = load_image(
|
| 49 |
+
"https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/astronaut.jpg"
|
| 50 |
+
)
|
| 51 |
+
init_image = init_image.resize((768, 512))
|
| 52 |
+
|
| 53 |
+
init_latent = remote_encode(
|
| 54 |
+
endpoint="https://whhx50ex1aryqvw6.us-east-1.aws.endpoints.huggingface.cloud",
|
| 55 |
+
image=init_image,
|
| 56 |
+
scaling_factor=0.3611,
|
| 57 |
+
shift_factor=0.1159
|
| 58 |
+
)
|
| 59 |
+
```
|
| 60 |
+
|
| 61 |
+
## Decoding
|
| 62 |
+
|
| 63 |
+
Decoding converts latent representations back into images or videos. Refer to the table below for the available and supported VAEs.
|
| 64 |
+
|
| 65 |
+
Set the output type to `"latent"` in the pipeline and set the `vae` to `None`. Pass the latents to the [`~utils.remote_decode`] function. For Flux, the latents are packed so the `height` and `width` also need to be passed. The specific `scaling_factor` and `shift_factor` values for each model can be found in the [Remote inference](../hybrid_inference/api_reference) API reference.
|
| 66 |
+
|
| 67 |
+
<hfoptions id="decode">
|
| 68 |
+
<hfoption id="Flux">
|
| 69 |
+
|
| 70 |
+
```py
|
| 71 |
+
from diffusers import FluxPipeline
|
| 72 |
+
|
| 73 |
+
pipeline = FluxPipeline.from_pretrained(
|
| 74 |
+
"black-forest-labs/FLUX.1-schnell",
|
| 75 |
+
torch_dtype=torch.bfloat16,
|
| 76 |
+
vae=None,
|
| 77 |
+
device_map="cuda"
|
| 78 |
+
)
|
| 79 |
+
|
| 80 |
+
prompt = """
|
| 81 |
+
A photorealistic Apollo-era photograph of a cat in a small astronaut suit with a bubble helmet, standing on the Moon and holding a flagpole planted in the dusty lunar soil. The flag shows a colorful paw-print emblem. Earth glows in the black sky above the stark gray surface, with sharp shadows and high-contrast lighting like vintage NASA photos.
|
| 82 |
+
"""
|
| 83 |
+
|
| 84 |
+
latent = pipeline(
|
| 85 |
+
prompt=prompt,
|
| 86 |
+
guidance_scale=0.0,
|
| 87 |
+
num_inference_steps=4,
|
| 88 |
+
output_type="latent",
|
| 89 |
+
).images
|
| 90 |
+
image = remote_decode(
|
| 91 |
+
endpoint="https://whhx50ex1aryqvw6.us-east-1.aws.endpoints.huggingface.cloud/",
|
| 92 |
+
tensor=latent,
|
| 93 |
+
height=1024,
|
| 94 |
+
width=1024,
|
| 95 |
+
scaling_factor=0.3611,
|
| 96 |
+
shift_factor=0.1159,
|
| 97 |
+
)
|
| 98 |
+
image.save("image.jpg")
|
| 99 |
+
```
|
| 100 |
+
|
| 101 |
+
</hfoption>
|
| 102 |
+
<hfoption id="HunyuanVideo">
|
| 103 |
+
|
| 104 |
+
```py
|
| 105 |
+
import torch
|
| 106 |
+
from diffusers import HunyuanVideoPipeline, HunyuanVideoTransformer3DModel
|
| 107 |
+
|
| 108 |
+
transformer = HunyuanVideoTransformer3DModel.from_pretrained(
|
| 109 |
+
"hunyuanvideo-community/HunyuanVideo", subfolder="transformer", torch_dtype=torch.bfloat16
|
| 110 |
+
)
|
| 111 |
+
pipeline = HunyuanVideoPipeline.from_pretrained(
|
| 112 |
+
model_id, transformer=transformer, vae=None, torch_dtype=torch.float16, device_map="cuda"
|
| 113 |
+
)
|
| 114 |
+
|
| 115 |
+
latent = pipeline(
|
| 116 |
+
prompt="A cat walks on the grass, realistic",
|
| 117 |
+
height=320,
|
| 118 |
+
width=512,
|
| 119 |
+
num_frames=61,
|
| 120 |
+
num_inference_steps=30,
|
| 121 |
+
output_type="latent",
|
| 122 |
+
).frames
|
| 123 |
+
|
| 124 |
+
video = remote_decode(
|
| 125 |
+
endpoint="https://o7ywnmrahorts457.us-east-1.aws.endpoints.huggingface.cloud/",
|
| 126 |
+
tensor=latent,
|
| 127 |
+
output_type="mp4",
|
| 128 |
+
)
|
| 129 |
+
|
| 130 |
+
if isinstance(video, bytes):
|
| 131 |
+
with open("video.mp4", "wb") as f:
|
| 132 |
+
f.write(video)
|
| 133 |
+
```
|
| 134 |
+
|
| 135 |
+
</hfoption>
|
| 136 |
+
</hfoptions>
|
| 137 |
+
|
| 138 |
+
## Queuing
|
| 139 |
+
|
| 140 |
+
Remote inference supports queuing to process multiple generation requests. While the current latent is being decoded, you can queue the next prompt.
|
| 141 |
+
|
| 142 |
+
```py
|
| 143 |
+
import queue
|
| 144 |
+
import threading
|
| 145 |
+
from IPython.display import display
|
| 146 |
+
from diffusers import StableDiffusionXLPipeline
|
| 147 |
+
|
| 148 |
+
def decode_worker(q: queue.Queue):
|
| 149 |
+
while True:
|
| 150 |
+
item = q.get()
|
| 151 |
+
if item is None:
|
| 152 |
+
break
|
| 153 |
+
image = remote_decode(
|
| 154 |
+
endpoint="https://q1bj3bpq6kzilnsu.us-east-1.aws.endpoints.huggingface.cloud/",
|
| 155 |
+
tensor=item,
|
| 156 |
+
scaling_factor=0.13025,
|
| 157 |
+
)
|
| 158 |
+
display(image)
|
| 159 |
+
q.task_done()
|
| 160 |
+
|
| 161 |
+
q = queue.Queue()
|
| 162 |
+
thread = threading.Thread(target=decode_worker, args=(q,), daemon=True)
|
| 163 |
+
thread.start()
|
| 164 |
+
|
| 165 |
+
def decode(latent: torch.Tensor):
|
| 166 |
+
q.put(latent)
|
| 167 |
+
|
| 168 |
+
prompts = [
|
| 169 |
+
"A grainy Apollo-era style photograph of a cat in a snug astronaut suit with a bubble helmet, standing on the lunar surface and gripping a flag with a paw-print emblem. The gray Moon landscape stretches behind it, Earth glowing vividly in the black sky, shadows crisp and high-contrast.",
|
| 170 |
+
"A vintage 1960s sci-fi pulp magazine cover illustration of a heroic cat astronaut planting a flag on the Moon. Bold, saturated colors, exaggerated space gear, playful typography floating in the background, Earth painted in bright blues and greens.",
|
| 171 |
+
"A hyper-detailed cinematic shot of a cat astronaut on the Moon holding a fluttering flag, fur visible through the helmet glass, lunar dust scattering under its feet. The vastness of space and Earth in the distance create an epic, awe-inspiring tone.",
|
| 172 |
+
"A colorful cartoon drawing of a happy cat wearing a chunky, oversized spacesuit, proudly holding a flag with a big paw print on it. The Moon’s surface is simplified with craters drawn like doodles, and Earth in the sky has a smiling face.",
|
| 173 |
+
"A monochrome 1969-style press photo of a “first cat on the Moon” moment. The cat, in a tiny astronaut suit, stands by a planted flag, with grainy textures, scratches, and a blurred Earth in the background, mimicking old archival space photos."
|
| 174 |
+
]
|
| 175 |
+
|
| 176 |
+
|
| 177 |
+
pipeline = StableDiffusionXLPipeline.from_pretrained(
|
| 178 |
+
"https://huggingface.co/stabilityai/stable-diffusion-xl-base-1.0",
|
| 179 |
+
torch_dtype=torch.float16,
|
| 180 |
+
vae=None,
|
| 181 |
+
device_map="cuda"
|
| 182 |
+
)
|
| 183 |
+
|
| 184 |
+
pipeline.unet = pipeline.unet.to(memory_format=torch.channels_last)
|
| 185 |
+
pipeline.unet = torch.compile(pipe.unet, mode="reduce-overhead", fullgraph=True)
|
| 186 |
+
|
| 187 |
+
_ = pipeline(
|
| 188 |
+
prompt=prompts[0],
|
| 189 |
+
output_type="latent",
|
| 190 |
+
)
|
| 191 |
+
|
| 192 |
+
for prompt in prompts:
|
| 193 |
+
latent = pipeline(
|
| 194 |
+
prompt=prompt,
|
| 195 |
+
output_type="latent",
|
| 196 |
+
).images
|
| 197 |
+
decode(latent)
|
| 198 |
+
|
| 199 |
+
q.put(None)
|
| 200 |
+
thread.join()
|
| 201 |
+
```
|
| 202 |
+
|
| 203 |
+
## Benchmarks
|
| 204 |
+
|
| 205 |
+
The tables demonstrate the memory requirements for encoding and decoding with Stable Diffusion v1.5 and SDXL on different GPUs.
|
| 206 |
+
|
| 207 |
+
For the majority of these GPUs, the memory usage dictates whether other models (text encoders, UNet/transformer) need to be offloaded or required tiled encoding. The latter two techniques increases inference time and impacts quality.
|
| 208 |
+
|
| 209 |
+
<details><summary>Encoding - Stable Diffusion v1.5</summary>
|
| 210 |
+
|
| 211 |
+
| GPU | Resolution | Time (seconds) | Memory (%) | Tiled Time (secs) | Tiled Memory (%) |
|
| 212 |
+
|:------------------------------|:-------------|-----------------:|-------------:|--------------------:|-------------------:|
|
| 213 |
+
| NVIDIA GeForce RTX 4090 | 512x512 | 0.015 | 3.51901 | 0.015 | 3.51901 |
|
| 214 |
+
| NVIDIA GeForce RTX 4090 | 256x256 | 0.004 | 1.3154 | 0.005 | 1.3154 |
|
| 215 |
+
| NVIDIA GeForce RTX 4090 | 2048x2048 | 0.402 | 47.1852 | 0.496 | 3.51901 |
|
| 216 |
+
| NVIDIA GeForce RTX 4090 | 1024x1024 | 0.078 | 12.2658 | 0.094 | 3.51901 |
|
| 217 |
+
| NVIDIA GeForce RTX 4080 SUPER | 512x512 | 0.023 | 5.30105 | 0.023 | 5.30105 |
|
| 218 |
+
| NVIDIA GeForce RTX 4080 SUPER | 256x256 | 0.006 | 1.98152 | 0.006 | 1.98152 |
|
| 219 |
+
| NVIDIA GeForce RTX 4080 SUPER | 2048x2048 | 0.574 | 71.08 | 0.656 | 5.30105 |
|
| 220 |
+
| NVIDIA GeForce RTX 4080 SUPER | 1024x1024 | 0.111 | 18.4772 | 0.14 | 5.30105 |
|
| 221 |
+
| NVIDIA GeForce RTX 3090 | 512x512 | 0.032 | 3.52782 | 0.032 | 3.52782 |
|
| 222 |
+
| NVIDIA GeForce RTX 3090 | 256x256 | 0.01 | 1.31869 | 0.009 | 1.31869 |
|
| 223 |
+
| NVIDIA GeForce RTX 3090 | 2048x2048 | 0.742 | 47.3033 | 0.954 | 3.52782 |
|
| 224 |
+
| NVIDIA GeForce RTX 3090 | 1024x1024 | 0.136 | 12.2965 | 0.207 | 3.52782 |
|
| 225 |
+
| NVIDIA GeForce RTX 3080 | 512x512 | 0.036 | 8.51761 | 0.036 | 8.51761 |
|
| 226 |
+
| NVIDIA GeForce RTX 3080 | 256x256 | 0.01 | 3.18387 | 0.01 | 3.18387 |
|
| 227 |
+
| NVIDIA GeForce RTX 3080 | 2048x2048 | 0.863 | 86.7424 | 1.191 | 8.51761 |
|
| 228 |
+
| NVIDIA GeForce RTX 3080 | 1024x1024 | 0.157 | 29.6888 | 0.227 | 8.51761 |
|
| 229 |
+
| NVIDIA GeForce RTX 3070 | 512x512 | 0.051 | 10.6941 | 0.051 | 10.6941 |
|
| 230 |
+
| NVIDIA GeForce RTX 3070 | 256x256 | 0.015 | 3.99743 | 0.015 | 3.99743 |
|
| 231 |
+
| NVIDIA GeForce RTX 3070 | 2048x2048 | 1.217 | 96.054 | 1.482 | 10.6941 |
|
| 232 |
+
| NVIDIA GeForce RTX 3070 | 1024x1024 | 0.223 | 37.2751 | 0.327 | 10.6941 |
|
| 233 |
+
|
| 234 |
+
</details>
|
| 235 |
+
|
| 236 |
+
<details><summary>Encoding SDXL</summary>
|
| 237 |
+
|
| 238 |
+
| GPU | Resolution | Time (seconds) | Memory Consumed (%) | Tiled Time (seconds) | Tiled Memory (%) |
|
| 239 |
+
|:------------------------------|:-------------|-----------------:|----------------------:|-----------------------:|-------------------:|
|
| 240 |
+
| NVIDIA GeForce RTX 4090 | 512x512 | 0.029 | 4.95707 | 0.029 | 4.95707 |
|
| 241 |
+
| NVIDIA GeForce RTX 4090 | 256x256 | 0.007 | 2.29666 | 0.007 | 2.29666 |
|
| 242 |
+
| NVIDIA GeForce RTX 4090 | 2048x2048 | 0.873 | 66.3452 | 0.863 | 15.5649 |
|
| 243 |
+
| NVIDIA GeForce RTX 4090 | 1024x1024 | 0.142 | 15.5479 | 0.143 | 15.5479 |
|
| 244 |
+
| NVIDIA GeForce RTX 4080 SUPER | 512x512 | 0.044 | 7.46735 | 0.044 | 7.46735 |
|
| 245 |
+
| NVIDIA GeForce RTX 4080 SUPER | 256x256 | 0.01 | 3.4597 | 0.01 | 3.4597 |
|
| 246 |
+
| NVIDIA GeForce RTX 4080 SUPER | 2048x2048 | 1.317 | 87.1615 | 1.291 | 23.447 |
|
| 247 |
+
| NVIDIA GeForce RTX 4080 SUPER | 1024x1024 | 0.213 | 23.4215 | 0.214 | 23.4215 |
|
| 248 |
+
| NVIDIA GeForce RTX 3090 | 512x512 | 0.058 | 5.65638 | 0.058 | 5.65638 |
|
| 249 |
+
| NVIDIA GeForce RTX 3090 | 256x256 | 0.016 | 2.45081 | 0.016 | 2.45081 |
|
| 250 |
+
| NVIDIA GeForce RTX 3090 | 2048x2048 | 1.755 | 77.8239 | 1.614 | 18.4193 |
|
| 251 |
+
| NVIDIA GeForce RTX 3090 | 1024x1024 | 0.265 | 18.4023 | 0.265 | 18.4023 |
|
| 252 |
+
| NVIDIA GeForce RTX 3080 | 512x512 | 0.064 | 13.6568 | 0.064 | 13.6568 |
|
| 253 |
+
| NVIDIA GeForce RTX 3080 | 256x256 | 0.018 | 5.91728 | 0.018 | 5.91728 |
|
| 254 |
+
| NVIDIA GeForce RTX 3080 | 2048x2048 | OOM | OOM | 1.866 | 44.4717 |
|
| 255 |
+
| NVIDIA GeForce RTX 3080 | 1024x1024 | 0.302 | 44.4308 | 0.302 | 44.4308 |
|
| 256 |
+
| NVIDIA GeForce RTX 3070 | 512x512 | 0.093 | 17.1465 | 0.093 | 17.1465 |
|
| 257 |
+
| NVIDIA GeForce RTX 3070 | 256x256 | 0.025 | 7.42931 | 0.026 | 7.42931 |
|
| 258 |
+
| NVIDIA GeForce RTX 3070 | 2048x2048 | OOM | OOM | 2.674 | 55.8355 |
|
| 259 |
+
| NVIDIA GeForce RTX 3070 | 1024x1024 | 0.443 | 55.7841 | 0.443 | 55.7841 |
|
| 260 |
+
|
| 261 |
+
</details>
|
| 262 |
+
|
| 263 |
+
<details><summary>Decoding - Stable Diffusion v1.5</summary>
|
| 264 |
+
|
| 265 |
+
| GPU | Resolution | Time (seconds) | Memory (%) | Tiled Time (secs) | Tiled Memory (%) |
|
| 266 |
+
| --- | --- | --- | --- | --- | --- |
|
| 267 |
+
| NVIDIA GeForce RTX 4090 | 512x512 | 0.031 | 5.60% | 0.031 (0%) | 5.60% |
|
| 268 |
+
| NVIDIA GeForce RTX 4090 | 1024x1024 | 0.148 | 20.00% | 0.301 (+103%) | 5.60% |
|
| 269 |
+
| NVIDIA GeForce RTX 4080 | 512x512 | 0.05 | 8.40% | 0.050 (0%) | 8.40% |
|
| 270 |
+
| NVIDIA GeForce RTX 4080 | 1024x1024 | 0.224 | 30.00% | 0.356 (+59%) | 8.40% |
|
| 271 |
+
| NVIDIA GeForce RTX 4070 Ti | 512x512 | 0.066 | 11.30% | 0.066 (0%) | 11.30% |
|
| 272 |
+
| NVIDIA GeForce RTX 4070 Ti | 1024x1024 | 0.284 | 40.50% | 0.454 (+60%) | 11.40% |
|
| 273 |
+
| NVIDIA GeForce RTX 3090 | 512x512 | 0.062 | 5.20% | 0.062 (0%) | 5.20% |
|
| 274 |
+
| NVIDIA GeForce RTX 3090 | 1024x1024 | 0.253 | 18.50% | 0.464 (+83%) | 5.20% |
|
| 275 |
+
| NVIDIA GeForce RTX 3080 | 512x512 | 0.07 | 12.80% | 0.070 (0%) | 12.80% |
|
| 276 |
+
| NVIDIA GeForce RTX 3080 | 1024x1024 | 0.286 | 45.30% | 0.466 (+63%) | 12.90% |
|
| 277 |
+
| NVIDIA GeForce RTX 3070 | 512x512 | 0.102 | 15.90% | 0.102 (0%) | 15.90% |
|
| 278 |
+
| NVIDIA GeForce RTX 3070 | 1024x1024 | 0.421 | 56.30% | 0.746 (+77%) | 16.00% |
|
| 279 |
+
|
| 280 |
+
</details>
|
| 281 |
+
|
| 282 |
+
<details><summary>Decoding SDXL</summary>
|
| 283 |
+
|
| 284 |
+
| GPU | Resolution | Time (seconds) | Memory Consumed (%) | Tiled Time (seconds) | Tiled Memory (%) |
|
| 285 |
+
| --- | --- | --- | --- | --- | --- |
|
| 286 |
+
| NVIDIA GeForce RTX 4090 | 512x512 | 0.057 | 10.00% | 0.057 (0%) | 10.00% |
|
| 287 |
+
| NVIDIA GeForce RTX 4090 | 1024x1024 | 0.256 | 35.50% | 0.257 (+0.4%) | 35.50% |
|
| 288 |
+
| NVIDIA GeForce RTX 4080 | 512x512 | 0.092 | 15.00% | 0.092 (0%) | 15.00% |
|
| 289 |
+
| NVIDIA GeForce RTX 4080 | 1024x1024 | 0.406 | 53.30% | 0.406 (0%) | 53.30% |
|
| 290 |
+
| NVIDIA GeForce RTX 4070 Ti | 512x512 | 0.121 | 20.20% | 0.120 (-0.8%) | 20.20% |
|
| 291 |
+
| NVIDIA GeForce RTX 4070 Ti | 1024x1024 | 0.519 | 72.00% | 0.519 (0%) | 72.00% |
|
| 292 |
+
| NVIDIA GeForce RTX 3090 | 512x512 | 0.107 | 10.50% | 0.107 (0%) | 10.50% |
|
| 293 |
+
| NVIDIA GeForce RTX 3090 | 1024x1024 | 0.459 | 38.00% | 0.460 (+0.2%) | 38.00% |
|
| 294 |
+
| NVIDIA GeForce RTX 3080 | 512x512 | 0.121 | 25.60% | 0.121 (0%) | 25.60% |
|
| 295 |
+
| NVIDIA GeForce RTX 3080 | 1024x1024 | 0.524 | 93.00% | 0.524 (0%) | 93.00% |
|
| 296 |
+
| NVIDIA GeForce RTX 3070 | 512x512 | 0.183 | 31.80% | 0.183 (0%) | 31.80% |
|
| 297 |
+
| NVIDIA GeForce RTX 3070 | 1024x1024 | 0.794 | 96.40% | 0.794 (0%) | 96.40% |
|
| 298 |
+
|
| 299 |
+
</details>
|
| 300 |
+
|
| 301 |
+
|
| 302 |
+
## Resources
|
| 303 |
+
|
| 304 |
+
- Remote inference is also supported in [SD.Next](https://github.com/vladmandic/sdnext) and [ComfyUI-HFRemoteVae](https://github.com/kijai/ComfyUI-HFRemoteVae).
|
| 305 |
+
- Refer to the [Remote VAEs for decoding with Inference Endpoints](https://huggingface.co/blog/remote_vae) blog post to learn more.
|
tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/imgs/access_request.png
ADDED

|
Git LFS Details
|
tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/imgs/diffusers_library.jpg
ADDED

|
Git LFS Details
|
tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/index.md
ADDED
|
@@ -0,0 +1,35 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
<p align="center">
|
| 14 |
+
<br>
|
| 15 |
+
<img src="https://raw.githubusercontent.com/huggingface/diffusers/77aadfee6a891ab9fcfb780f87c693f7a5beeb8e/docs/source/imgs/diffusers_library.jpg" width="400" style="border: none;"/>
|
| 16 |
+
<br>
|
| 17 |
+
</p>
|
| 18 |
+
|
| 19 |
+
# Diffusers
|
| 20 |
+
|
| 21 |
+
Diffusers is a library of state-of-the-art pretrained diffusion models for generating videos, images, and audio.
|
| 22 |
+
|
| 23 |
+
The library revolves around the [`DiffusionPipeline`], an API designed for:
|
| 24 |
+
|
| 25 |
+
- easy inference with only a few lines of code
|
| 26 |
+
- flexibility to mix-and-match pipeline components (models, schedulers)
|
| 27 |
+
- loading and using adapters like LoRA
|
| 28 |
+
|
| 29 |
+
Diffusers also comes with optimizations - such as offloading and quantization - to ensure even the largest models are accessible on memory-constrained devices. If memory is not an issue, Diffusers supports torch.compile to boost inference speed.
|
| 30 |
+
|
| 31 |
+
Get started right away with a Diffusers model on the [Hub](https://huggingface.co/models?library=diffusers&sort=trending) today!
|
| 32 |
+
|
| 33 |
+
## Learn
|
| 34 |
+
|
| 35 |
+
If you're a beginner, we recommend starting with the [Hugging Face Diffusion Models Course](https://huggingface.co/learn/diffusion-course/unit0/1). You'll learn the theory behind diffusion models, and learn how to use the Diffusers library to generate images, fine-tune your own models, and more.
|
tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/installation.md
ADDED
|
@@ -0,0 +1,146 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Installation
|
| 14 |
+
|
| 15 |
+
Diffusers is tested on Python 3.8+ and PyTorch 1.4+. Install [PyTorch](https://pytorch.org/get-started/locally/) according to your system and setup.
|
| 16 |
+
|
| 17 |
+
Create a [virtual environment](https://packaging.python.org/guides/installing-using-pip-and-virtual-environments/) for easier management of separate projects and to avoid compatibility issues between dependencies. Use [uv](https://docs.astral.sh/uv/), a Rust-based Python package and project manager, to create a virtual environment and install Diffusers.
|
| 18 |
+
|
| 19 |
+
```bash
|
| 20 |
+
uv venv my-env
|
| 21 |
+
source my-env/bin/activate
|
| 22 |
+
```
|
| 23 |
+
|
| 24 |
+
Install Diffusers with one of the following methods.
|
| 25 |
+
|
| 26 |
+
<hfoptions id="install">
|
| 27 |
+
<hfoption id="pip">
|
| 28 |
+
|
| 29 |
+
PyTorch only supports Python 3.8 - 3.11 on Windows.
|
| 30 |
+
|
| 31 |
+
```bash
|
| 32 |
+
uv pip install diffusers["torch"] transformers
|
| 33 |
+
```
|
| 34 |
+
|
| 35 |
+
</hfoption>
|
| 36 |
+
<hfoption id="conda">
|
| 37 |
+
|
| 38 |
+
```bash
|
| 39 |
+
conda install -c conda-forge diffusers
|
| 40 |
+
```
|
| 41 |
+
|
| 42 |
+
</hfoption>
|
| 43 |
+
<hfoption id="source">
|
| 44 |
+
|
| 45 |
+
A source install installs the `main` version instead of the latest `stable` version. The `main` version is useful for staying updated with the latest changes but it may not always be stable. If you run into a problem, open an [Issue](https://github.com/huggingface/diffusers/issues/new/choose) and we will try to resolve it as soon as possible.
|
| 46 |
+
|
| 47 |
+
Make sure [Accelerate](https://huggingface.co/docs/accelerate/index) is installed.
|
| 48 |
+
|
| 49 |
+
```bash
|
| 50 |
+
uv pip install accelerate
|
| 51 |
+
```
|
| 52 |
+
|
| 53 |
+
Install Diffusers from source with the command below.
|
| 54 |
+
|
| 55 |
+
```bash
|
| 56 |
+
uv pip install git+https://github.com/huggingface/diffusers
|
| 57 |
+
```
|
| 58 |
+
|
| 59 |
+
</hfoption>
|
| 60 |
+
</hfoptions>
|
| 61 |
+
|
| 62 |
+
## Editable install
|
| 63 |
+
|
| 64 |
+
An editable install is recommended for development workflows or if you're using the `main` version of the source code. A special link is created between the cloned repository and the Python library paths. This avoids reinstalling a package after every change.
|
| 65 |
+
|
| 66 |
+
Clone the repository and install Diffusers with the following commands.
|
| 67 |
+
|
| 68 |
+
```bash
|
| 69 |
+
git clone https://github.com/huggingface/diffusers.git
|
| 70 |
+
cd diffusers
|
| 71 |
+
uv pip install -e ".[torch]"
|
| 72 |
+
```
|
| 73 |
+
|
| 74 |
+
> [!WARNING]
|
| 75 |
+
> You must keep the `diffusers` folder if you want to keep using the library with the editable install.
|
| 76 |
+
|
| 77 |
+
Update your cloned repository to the latest version of Diffusers with the command below.
|
| 78 |
+
|
| 79 |
+
```bash
|
| 80 |
+
cd ~/diffusers/
|
| 81 |
+
git pull
|
| 82 |
+
```
|
| 83 |
+
|
| 84 |
+
## Cache
|
| 85 |
+
|
| 86 |
+
Model weights and files are downloaded from the Hub to a cache, which is usually your home directory. Change the cache location with the [HF_HOME](https://huggingface.co/docs/huggingface_hub/package_reference/environment_variables#hfhome) or [HF_HUB_CACHE](https://huggingface.co/docs/huggingface_hub/package_reference/environment_variables#hfhubcache) environment variables or configuring the `cache_dir` parameter in methods like [`~DiffusionPipeline.from_pretrained`].
|
| 87 |
+
|
| 88 |
+
<hfoptions id="cache">
|
| 89 |
+
<hfoption id="env variable">
|
| 90 |
+
|
| 91 |
+
```bash
|
| 92 |
+
export HF_HOME="/path/to/your/cache"
|
| 93 |
+
export HF_HUB_CACHE="/path/to/your/hub/cache"
|
| 94 |
+
```
|
| 95 |
+
|
| 96 |
+
</hfoption>
|
| 97 |
+
<hfoption id="from_pretrained">
|
| 98 |
+
|
| 99 |
+
```py
|
| 100 |
+
from diffusers import DiffusionPipeline
|
| 101 |
+
|
| 102 |
+
pipeline = DiffusionPipeline.from_pretrained(
|
| 103 |
+
"black-forest-labs/FLUX.1-dev",
|
| 104 |
+
cache_dir="/path/to/your/cache"
|
| 105 |
+
)
|
| 106 |
+
```
|
| 107 |
+
|
| 108 |
+
</hfoption>
|
| 109 |
+
</hfoptions>
|
| 110 |
+
|
| 111 |
+
Cached files allow you to use Diffusers offline. Set the [HF_HUB_OFFLINE](https://huggingface.co/docs/huggingface_hub/package_reference/environment_variables#hfhuboffline) environment variable to `1` to prevent Diffusers from connecting to the internet.
|
| 112 |
+
|
| 113 |
+
```shell
|
| 114 |
+
export HF_HUB_OFFLINE=1
|
| 115 |
+
```
|
| 116 |
+
|
| 117 |
+
For more details about managing and cleaning the cache, take a look at the [Understand caching](https://huggingface.co/docs/huggingface_hub/guides/manage-cache) guide.
|
| 118 |
+
|
| 119 |
+
## Telemetry logging
|
| 120 |
+
|
| 121 |
+
Diffusers gathers telemetry information during [`~DiffusionPipeline.from_pretrained`] requests.
|
| 122 |
+
The data gathered includes the Diffusers and PyTorch version, the requested model or pipeline class,
|
| 123 |
+
and the path to a pretrained checkpoint if it is hosted on the Hub.
|
| 124 |
+
|
| 125 |
+
This usage data helps us debug issues and prioritize new features.
|
| 126 |
+
Telemetry is only sent when loading models and pipelines from the Hub,
|
| 127 |
+
and it is not collected if you're loading local files.
|
| 128 |
+
|
| 129 |
+
Opt-out and disable telemetry collection with the [HF_HUB_DISABLE_TELEMETRY](https://huggingface.co/docs/huggingface_hub/package_reference/environment_variables#hfhubdisabletelemetry) environment variable.
|
| 130 |
+
|
| 131 |
+
<hfoptions id="telemetry">
|
| 132 |
+
<hfoption id="Linux/macOS">
|
| 133 |
+
|
| 134 |
+
```bash
|
| 135 |
+
export HF_HUB_DISABLE_TELEMETRY=1
|
| 136 |
+
```
|
| 137 |
+
|
| 138 |
+
</hfoption>
|
| 139 |
+
<hfoption id="Windows">
|
| 140 |
+
|
| 141 |
+
```bash
|
| 142 |
+
set HF_HUB_DISABLE_TELEMETRY=1
|
| 143 |
+
```
|
| 144 |
+
|
| 145 |
+
</hfoption>
|
| 146 |
+
</hfoptions>
|
tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/modular_diffusers/auto_pipeline_blocks.md
ADDED
|
@@ -0,0 +1,225 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# AutoPipelineBlocks
|
| 14 |
+
|
| 15 |
+
[`~modular_pipelines.AutoPipelineBlocks`] are a multi-block type containing blocks that support different workflows. It automatically selects which sub-blocks to run based on the input provided at runtime. This is typically used to package multiple workflows - text-to-image, image-to-image, inpaint - into a single pipeline for convenience.
|
| 16 |
+
|
| 17 |
+
This guide shows how to create [`~modular_pipelines.AutoPipelineBlocks`].
|
| 18 |
+
|
| 19 |
+
Create three [`~modular_pipelines.ModularPipelineBlocks`] for text-to-image, image-to-image, and inpainting. These represent the different workflows available in the pipeline.
|
| 20 |
+
|
| 21 |
+
<hfoptions id="auto">
|
| 22 |
+
<hfoption id="text-to-image">
|
| 23 |
+
|
| 24 |
+
```py
|
| 25 |
+
import torch
|
| 26 |
+
from diffusers.modular_pipelines import ModularPipelineBlocks, InputParam, OutputParam
|
| 27 |
+
|
| 28 |
+
class TextToImageBlock(ModularPipelineBlocks):
|
| 29 |
+
model_name = "text2img"
|
| 30 |
+
|
| 31 |
+
@property
|
| 32 |
+
def inputs(self):
|
| 33 |
+
return [InputParam(name="prompt")]
|
| 34 |
+
|
| 35 |
+
@property
|
| 36 |
+
def intermediate_outputs(self):
|
| 37 |
+
return []
|
| 38 |
+
|
| 39 |
+
@property
|
| 40 |
+
def description(self):
|
| 41 |
+
return "I'm a text-to-image workflow!"
|
| 42 |
+
|
| 43 |
+
def __call__(self, components, state):
|
| 44 |
+
block_state = self.get_block_state(state)
|
| 45 |
+
print("running the text-to-image workflow")
|
| 46 |
+
# Add your text-to-image logic here
|
| 47 |
+
# For example: generate image from prompt
|
| 48 |
+
self.set_block_state(state, block_state)
|
| 49 |
+
return components, state
|
| 50 |
+
```
|
| 51 |
+
|
| 52 |
+
|
| 53 |
+
</hfoption>
|
| 54 |
+
<hfoption id="image-to-image">
|
| 55 |
+
|
| 56 |
+
```py
|
| 57 |
+
class ImageToImageBlock(ModularPipelineBlocks):
|
| 58 |
+
model_name = "img2img"
|
| 59 |
+
|
| 60 |
+
@property
|
| 61 |
+
def inputs(self):
|
| 62 |
+
return [InputParam(name="prompt"), InputParam(name="image")]
|
| 63 |
+
|
| 64 |
+
@property
|
| 65 |
+
def intermediate_outputs(self):
|
| 66 |
+
return []
|
| 67 |
+
|
| 68 |
+
@property
|
| 69 |
+
def description(self):
|
| 70 |
+
return "I'm an image-to-image workflow!"
|
| 71 |
+
|
| 72 |
+
def __call__(self, components, state):
|
| 73 |
+
block_state = self.get_block_state(state)
|
| 74 |
+
print("running the image-to-image workflow")
|
| 75 |
+
# Add your image-to-image logic here
|
| 76 |
+
# For example: transform input image based on prompt
|
| 77 |
+
self.set_block_state(state, block_state)
|
| 78 |
+
return components, state
|
| 79 |
+
```
|
| 80 |
+
|
| 81 |
+
|
| 82 |
+
</hfoption>
|
| 83 |
+
<hfoption id="inpaint">
|
| 84 |
+
|
| 85 |
+
```py
|
| 86 |
+
class InpaintBlock(ModularPipelineBlocks):
|
| 87 |
+
model_name = "inpaint"
|
| 88 |
+
|
| 89 |
+
@property
|
| 90 |
+
def inputs(self):
|
| 91 |
+
return [InputParam(name="prompt"), InputParam(name="image"), InputParam(name="mask")]
|
| 92 |
+
|
| 93 |
+
@property
|
| 94 |
+
def intermediate_outputs(self):
|
| 95 |
+
return []
|
| 96 |
+
|
| 97 |
+
@property
|
| 98 |
+
def description(self):
|
| 99 |
+
return "I'm an inpaint workflow!"
|
| 100 |
+
|
| 101 |
+
def __call__(self, components, state):
|
| 102 |
+
block_state = self.get_block_state(state)
|
| 103 |
+
print("running the inpaint workflow")
|
| 104 |
+
# Add your inpainting logic here
|
| 105 |
+
# For example: fill masked areas based on prompt
|
| 106 |
+
self.set_block_state(state, block_state)
|
| 107 |
+
return components, state
|
| 108 |
+
```
|
| 109 |
+
|
| 110 |
+
</hfoption>
|
| 111 |
+
</hfoptions>
|
| 112 |
+
|
| 113 |
+
Create an [`~modular_pipelines.AutoPipelineBlocks`] class that includes a list of the sub-block classes and their corresponding block names.
|
| 114 |
+
|
| 115 |
+
You also need to include `block_trigger_inputs`, a list of input names that trigger the corresponding block. If a trigger input is provided at runtime, then that block is selected to run. Use `None` to specify the default block to run if no trigger inputs are detected.
|
| 116 |
+
|
| 117 |
+
Lastly, it is important to include a `description` that clearly explains which inputs trigger which workflow. This helps users understand how to run specific workflows.
|
| 118 |
+
|
| 119 |
+
```py
|
| 120 |
+
from diffusers.modular_pipelines import AutoPipelineBlocks
|
| 121 |
+
|
| 122 |
+
class AutoImageBlocks(AutoPipelineBlocks):
|
| 123 |
+
# List of sub-block classes to choose from
|
| 124 |
+
block_classes = [InpaintBlock, ImageToImageBlock, TextToImageBlock]
|
| 125 |
+
# Names for each block in the same order
|
| 126 |
+
block_names = ["inpaint", "img2img", "text2img"]
|
| 127 |
+
# Trigger inputs that determine which block to run
|
| 128 |
+
# - "mask" triggers inpaint workflow
|
| 129 |
+
# - "image" triggers img2img workflow (but only if mask is not provided)
|
| 130 |
+
# - if none of above, runs the text2img workflow (default)
|
| 131 |
+
block_trigger_inputs = ["mask", "image", None]
|
| 132 |
+
|
| 133 |
+
@property
|
| 134 |
+
def description(self):
|
| 135 |
+
return (
|
| 136 |
+
"Pipeline generates images given different types of conditions!\n"
|
| 137 |
+
+ "This is an auto pipeline block that works for text2img, img2img and inpainting tasks.\n"
|
| 138 |
+
+ " - inpaint workflow is run when `mask` is provided.\n"
|
| 139 |
+
+ " - img2img workflow is run when `image` is provided (but only when `mask` is not provided).\n"
|
| 140 |
+
+ " - text2img workflow is run when neither `image` nor `mask` is provided.\n"
|
| 141 |
+
)
|
| 142 |
+
```
|
| 143 |
+
|
| 144 |
+
It is **very** important to include a `description` to avoid any confusion over how to run a block and what inputs are required. While [`~modular_pipelines.AutoPipelineBlocks`] are convenient, its conditional logic may be difficult to figure out if it isn't properly explained.
|
| 145 |
+
|
| 146 |
+
Create an instance of `AutoImageBlocks`.
|
| 147 |
+
|
| 148 |
+
```py
|
| 149 |
+
auto_blocks = AutoImageBlocks()
|
| 150 |
+
```
|
| 151 |
+
|
| 152 |
+
For more complex compositions, such as nested [`~modular_pipelines.AutoPipelineBlocks`] blocks when they're used as sub-blocks in larger pipelines, use the [`~modular_pipelines.SequentialPipelineBlocks.get_execution_blocks`] method to extract the a block that is actually run based on your input.
|
| 153 |
+
|
| 154 |
+
```py
|
| 155 |
+
auto_blocks.get_execution_blocks(mask=True)
|
| 156 |
+
```
|
| 157 |
+
|
| 158 |
+
## ConditionalPipelineBlocks
|
| 159 |
+
|
| 160 |
+
[`~modular_pipelines.AutoPipelineBlocks`] is a special case of [`~modular_pipelines.ConditionalPipelineBlocks`]. While [`~modular_pipelines.AutoPipelineBlocks`] selects blocks based on whether a trigger input is provided or not, [`~modular_pipelines.ConditionalPipelineBlocks`] is able to select a block based on custom selection logic provided in the `select_block` method.
|
| 161 |
+
|
| 162 |
+
Here is the same example written using [`~modular_pipelines.ConditionalPipelineBlocks`] directly:
|
| 163 |
+
|
| 164 |
+
```py
|
| 165 |
+
from diffusers.modular_pipelines import ConditionalPipelineBlocks
|
| 166 |
+
|
| 167 |
+
class AutoImageBlocks(ConditionalPipelineBlocks):
|
| 168 |
+
block_classes = [InpaintBlock, ImageToImageBlock, TextToImageBlock]
|
| 169 |
+
block_names = ["inpaint", "img2img", "text2img"]
|
| 170 |
+
block_trigger_inputs = ["mask", "image"]
|
| 171 |
+
default_block_name = "text2img"
|
| 172 |
+
|
| 173 |
+
@property
|
| 174 |
+
def description(self):
|
| 175 |
+
return (
|
| 176 |
+
"Pipeline generates images given different types of conditions!\n"
|
| 177 |
+
+ "This is an auto pipeline block that works for text2img, img2img and inpainting tasks.\n"
|
| 178 |
+
+ " - inpaint workflow is run when `mask` is provided.\n"
|
| 179 |
+
+ " - img2img workflow is run when `image` is provided (but only when `mask` is not provided).\n"
|
| 180 |
+
+ " - text2img workflow is run when neither `image` nor `mask` is provided.\n"
|
| 181 |
+
)
|
| 182 |
+
|
| 183 |
+
def select_block(self, mask=None, image=None) -> str | None:
|
| 184 |
+
if mask is not None:
|
| 185 |
+
return "inpaint"
|
| 186 |
+
if image is not None:
|
| 187 |
+
return "img2img"
|
| 188 |
+
return None # falls back to default_block_name ("text2img")
|
| 189 |
+
```
|
| 190 |
+
|
| 191 |
+
The inputs listed in `block_trigger_inputs` are passed as keyword arguments to `select_block()`. When `select_block` returns `None`, it falls back to `default_block_name`. If `default_block_name` is also `None`, the entire conditional block is skipped — this is useful for optional processing steps that should only run when specific inputs are provided.
|
| 192 |
+
|
| 193 |
+
## Workflows
|
| 194 |
+
|
| 195 |
+
Pipelines that contain conditional blocks ([`~modular_pipelines.AutoPipelineBlocks`] or [`~modular_pipelines.ConditionalPipelineBlocks]`) can support multiple workflows — for example, our SDXL modular pipeline supports a dozen workflows all in one pipeline. But this also means it can be confusing for users to know what workflows are supported and how to run them. For pipeline builders, it's useful to be able to extract only the blocks relevant to a specific workflow.
|
| 196 |
+
|
| 197 |
+
We recommend defining a `_workflow_map` to give each workflow a name and explicitly list the inputs it requires.
|
| 198 |
+
|
| 199 |
+
```py
|
| 200 |
+
from diffusers.modular_pipelines import SequentialPipelineBlocks
|
| 201 |
+
|
| 202 |
+
class MyPipelineBlocks(SequentialPipelineBlocks):
|
| 203 |
+
block_classes = [TextEncoderBlock, AutoImageBlocks, DecodeBlock]
|
| 204 |
+
block_names = ["text_encoder", "auto_image", "decode"]
|
| 205 |
+
|
| 206 |
+
_workflow_map = {
|
| 207 |
+
"text2image": {"prompt": True},
|
| 208 |
+
"image2image": {"image": True, "prompt": True},
|
| 209 |
+
"inpaint": {"mask": True, "image": True, "prompt": True},
|
| 210 |
+
}
|
| 211 |
+
```
|
| 212 |
+
|
| 213 |
+
All of our built-in modular pipelines come with pre-defined workflows. The `available_workflows` property lists all supported workflows:
|
| 214 |
+
|
| 215 |
+
```py
|
| 216 |
+
pipeline_blocks = MyPipelineBlocks()
|
| 217 |
+
pipeline_blocks.available_workflows
|
| 218 |
+
# ['text2image', 'image2image', 'inpaint']
|
| 219 |
+
```
|
| 220 |
+
|
| 221 |
+
Retrieve a specific workflow with `get_workflow` to inspect and debug a specific block that executes the workflow.
|
| 222 |
+
|
| 223 |
+
```py
|
| 224 |
+
pipeline_blocks.get_workflow("inpaint")
|
| 225 |
+
```
|
tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/modular_diffusers/components_manager.md
ADDED
|
@@ -0,0 +1,96 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# ComponentsManager
|
| 14 |
+
|
| 15 |
+
The [`ComponentsManager`] is a model registry and management system for Modular Diffusers. It adds and tracks models, stores useful metadata (model size, device placement, adapters), and supports offloading.
|
| 16 |
+
|
| 17 |
+
This guide will show you how to use [`ComponentsManager`] to manage components and device memory.
|
| 18 |
+
|
| 19 |
+
## Connect to a pipeline
|
| 20 |
+
|
| 21 |
+
Create a [`ComponentsManager`] and pass it to a [`ModularPipeline`] with either [`~ModularPipeline.from_pretrained`] or [`~ModularPipelineBlocks.init_pipeline`].
|
| 22 |
+
|
| 23 |
+
|
| 24 |
+
<hfoptions id="create">
|
| 25 |
+
<hfoption id="from_pretrained">
|
| 26 |
+
|
| 27 |
+
```py
|
| 28 |
+
from diffusers import ModularPipeline, ComponentsManager
|
| 29 |
+
import torch
|
| 30 |
+
|
| 31 |
+
manager = ComponentsManager()
|
| 32 |
+
pipe = ModularPipeline.from_pretrained("Tongyi-MAI/Z-Image-Turbo", components_manager=manager)
|
| 33 |
+
pipe.load_components(torch_dtype=torch.bfloat16)
|
| 34 |
+
```
|
| 35 |
+
|
| 36 |
+
</hfoption>
|
| 37 |
+
<hfoption id="init_pipeline">
|
| 38 |
+
|
| 39 |
+
```py
|
| 40 |
+
from diffusers import ModularPipelineBlocks, ComponentsManager
|
| 41 |
+
import torch
|
| 42 |
+
manager = ComponentsManager()
|
| 43 |
+
blocks = ModularPipelineBlocks.from_pretrained("diffusers/Florence2-image-Annotator", trust_remote_code=True)
|
| 44 |
+
pipe= blocks.init_pipeline(components_manager=manager)
|
| 45 |
+
pipe.load_components(torch_dtype=torch.bfloat16)
|
| 46 |
+
```
|
| 47 |
+
|
| 48 |
+
</hfoption>
|
| 49 |
+
</hfoptions>
|
| 50 |
+
|
| 51 |
+
Components loaded by the pipeline are automatically registered in the manager. You can inspect them right away.
|
| 52 |
+
|
| 53 |
+
## Inspect components
|
| 54 |
+
|
| 55 |
+
Print the [`ComponentsManager`] to see all registered components, including their class, device placement, dtype, memory size, and load ID.
|
| 56 |
+
|
| 57 |
+
The output below corresponds to the `from_pretrained` example above.
|
| 58 |
+
|
| 59 |
+
```py
|
| 60 |
+
Components:
|
| 61 |
+
=============================================================================================================================
|
| 62 |
+
Models:
|
| 63 |
+
-----------------------------------------------------------------------------------------------------------------------------
|
| 64 |
+
Name_ID | Class | Device: act(exec) | Dtype | Size (GB) | Load ID
|
| 65 |
+
-----------------------------------------------------------------------------------------------------------------------------
|
| 66 |
+
text_encoder_140458257514752 | Qwen3Model | cpu | torch.bfloat16 | 7.49 | Tongyi-MAI/Z-Image-Turbo|text_encoder|null|null
|
| 67 |
+
vae_140458257515376 | AutoencoderKL | cpu | torch.bfloat16 | 0.16 | Tongyi-MAI/Z-Image-Turbo|vae|null|null
|
| 68 |
+
transformer_140458257515616 | ZImageTransformer2DModel | cpu | torch.bfloat16 | 11.46 | Tongyi-MAI/Z-Image-Turbo|transformer|null|null
|
| 69 |
+
-----------------------------------------------------------------------------------------------------------------------------
|
| 70 |
+
|
| 71 |
+
Other Components:
|
| 72 |
+
-----------------------------------------------------------------------------------------------------------------------------
|
| 73 |
+
ID | Class | Collection
|
| 74 |
+
-----------------------------------------------------------------------------------------------------------------------------
|
| 75 |
+
scheduler_140461023555264 | FlowMatchEulerDiscreteScheduler | N/A
|
| 76 |
+
tokenizer_140458256346432 | Qwen2Tokenizer | N/A
|
| 77 |
+
-----------------------------------------------------------------------------------------------------------------------------
|
| 78 |
+
```
|
| 79 |
+
|
| 80 |
+
The table shows models (with device, dtype, and memory info) separately from other components like schedulers and tokenizers. If any models have LoRA adapters, IP-Adapters, or quantization applied, that information is displayed in an additional section at the bottom.
|
| 81 |
+
|
| 82 |
+
## Offloading
|
| 83 |
+
|
| 84 |
+
The [`~ComponentsManager.enable_auto_cpu_offload`] method is a global offloading strategy that works across all models regardless of which pipeline is using them. Once enabled, you don't need to worry about device placement if you add or remove components.
|
| 85 |
+
|
| 86 |
+
```py
|
| 87 |
+
manager.enable_auto_cpu_offload(device="cuda")
|
| 88 |
+
```
|
| 89 |
+
|
| 90 |
+
All models begin on the CPU and [`ComponentsManager`] moves them to the appropriate device right before they're needed, and moves other models back to the CPU when GPU memory is low.
|
| 91 |
+
|
| 92 |
+
Call [`~ComponentsManager.disable_auto_cpu_offload`] to disable offloading.
|
| 93 |
+
|
| 94 |
+
```py
|
| 95 |
+
manager.disable_auto_cpu_offload()
|
| 96 |
+
```
|
tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/modular_diffusers/custom_blocks.md
ADDED
|
@@ -0,0 +1,335 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
|
| 14 |
+
# Building Custom Blocks
|
| 15 |
+
|
| 16 |
+
[ModularPipelineBlocks](./pipeline_block) are the fundamental building blocks of a [`ModularPipeline`]. You can create custom blocks by defining their inputs, outputs, and computation logic. This guide demonstrates how to create and use a custom block.
|
| 17 |
+
|
| 18 |
+
> [!TIP]
|
| 19 |
+
> Explore the [Modular Diffusers Custom Blocks](https://huggingface.co/collections/diffusers/modular-diffusers-custom-blocks) collection for official custom blocks.
|
| 20 |
+
|
| 21 |
+
## Project Structure
|
| 22 |
+
|
| 23 |
+
Your custom block project should use the following structure:
|
| 24 |
+
|
| 25 |
+
```shell
|
| 26 |
+
.
|
| 27 |
+
├── block.py
|
| 28 |
+
└── modular_config.json
|
| 29 |
+
```
|
| 30 |
+
|
| 31 |
+
- `block.py` contains the custom block implementation
|
| 32 |
+
- `modular_config.json` contains the metadata needed to load the block
|
| 33 |
+
|
| 34 |
+
## Quick Start with Template
|
| 35 |
+
|
| 36 |
+
The fastest way to create a custom block is to start from our template. The template provides a pre-configured project structure with `block.py` and `modular_config.json` files, plus commented examples showing how to define components, inputs, outputs, and the `__call__` method—so you can focus on your custom logic instead of boilerplate setup.
|
| 37 |
+
|
| 38 |
+
### Download the template
|
| 39 |
+
|
| 40 |
+
```python
|
| 41 |
+
from diffusers import ModularPipelineBlocks
|
| 42 |
+
|
| 43 |
+
model_id = "diffusers/custom-block-template"
|
| 44 |
+
local_dir = model_id.split("/")[-1]
|
| 45 |
+
|
| 46 |
+
blocks = ModularPipelineBlocks.from_pretrained(
|
| 47 |
+
model_id,
|
| 48 |
+
trust_remote_code=True,
|
| 49 |
+
local_dir=local_dir
|
| 50 |
+
)
|
| 51 |
+
```
|
| 52 |
+
|
| 53 |
+
This saves the template files to `custom-block-template/` locally or you could use `local_dir` to save to a specific location.
|
| 54 |
+
|
| 55 |
+
### Edit locally
|
| 56 |
+
|
| 57 |
+
Open `block.py` and implement your custom block. The template includes commented examples showing how to define each property. See the [Florence-2 example](#example-florence-2-image-annotator) below for a complete implementation.
|
| 58 |
+
|
| 59 |
+
### Test your block
|
| 60 |
+
|
| 61 |
+
```python
|
| 62 |
+
from diffusers import ModularPipelineBlocks
|
| 63 |
+
|
| 64 |
+
blocks = ModularPipelineBlocks.from_pretrained(local_dir, trust_remote_code=True)
|
| 65 |
+
pipeline = blocks.init_pipeline()
|
| 66 |
+
output = pipeline(...) # your inputs here
|
| 67 |
+
```
|
| 68 |
+
|
| 69 |
+
### Upload to the Hub
|
| 70 |
+
|
| 71 |
+
```python
|
| 72 |
+
pipeline.save_pretrained(local_dir, repo_id="your-username/your-block-name", push_to_hub=True)
|
| 73 |
+
```
|
| 74 |
+
|
| 75 |
+
## Example: Florence-2 Image Annotator
|
| 76 |
+
|
| 77 |
+
This example creates a custom block with [Florence-2](https://huggingface.co/docs/transformers/model_doc/florence2) to process an input image and generate a mask for inpainting.
|
| 78 |
+
|
| 79 |
+
### Define components
|
| 80 |
+
|
| 81 |
+
Define the components the block needs, `Florence2ForConditionalGeneration` and its processor. When defining components, specify the `name` (how you'll access it in code), `type_hint` (the model class), and `pretrained_model_name_or_path` (where to load weights from).
|
| 82 |
+
|
| 83 |
+
```python
|
| 84 |
+
# Inside block.py
|
| 85 |
+
from diffusers.modular_pipelines import ModularPipelineBlocks, ComponentSpec
|
| 86 |
+
from transformers import AutoProcessor, Florence2ForConditionalGeneration
|
| 87 |
+
|
| 88 |
+
|
| 89 |
+
class Florence2ImageAnnotatorBlock(ModularPipelineBlocks):
|
| 90 |
+
|
| 91 |
+
@property
|
| 92 |
+
def expected_components(self):
|
| 93 |
+
return [
|
| 94 |
+
ComponentSpec(
|
| 95 |
+
name="image_annotator",
|
| 96 |
+
type_hint=Florence2ForConditionalGeneration,
|
| 97 |
+
pretrained_model_name_or_path="florence-community/Florence-2-base-ft",
|
| 98 |
+
),
|
| 99 |
+
ComponentSpec(
|
| 100 |
+
name="image_annotator_processor",
|
| 101 |
+
type_hint=AutoProcessor,
|
| 102 |
+
pretrained_model_name_or_path="florence-community/Florence-2-base-ft",
|
| 103 |
+
),
|
| 104 |
+
]
|
| 105 |
+
```
|
| 106 |
+
|
| 107 |
+
### Define inputs and outputs
|
| 108 |
+
|
| 109 |
+
Inputs include the image, annotation task, and prompt. Outputs include the generated mask and annotations.
|
| 110 |
+
|
| 111 |
+
```python
|
| 112 |
+
from typing import List, Union
|
| 113 |
+
from PIL import Image
|
| 114 |
+
from diffusers.modular_pipelines import InputParam, OutputParam
|
| 115 |
+
|
| 116 |
+
|
| 117 |
+
class Florence2ImageAnnotatorBlock(ModularPipelineBlocks):
|
| 118 |
+
|
| 119 |
+
# ... expected_components from above ...
|
| 120 |
+
|
| 121 |
+
@property
|
| 122 |
+
def inputs(self) -> List[InputParam]:
|
| 123 |
+
return [
|
| 124 |
+
InputParam(
|
| 125 |
+
"image",
|
| 126 |
+
type_hint=Union[Image.Image, List[Image.Image]],
|
| 127 |
+
required=True,
|
| 128 |
+
description="Image(s) to annotate",
|
| 129 |
+
),
|
| 130 |
+
InputParam(
|
| 131 |
+
"annotation_task",
|
| 132 |
+
type_hint=str,
|
| 133 |
+
default="<REFERRING_EXPRESSION_SEGMENTATION>",
|
| 134 |
+
description="Annotation task to perform (e.g., <OD>, <CAPTION>, <REFERRING_EXPRESSION_SEGMENTATION>)",
|
| 135 |
+
),
|
| 136 |
+
InputParam(
|
| 137 |
+
"annotation_prompt",
|
| 138 |
+
type_hint=str,
|
| 139 |
+
required=True,
|
| 140 |
+
description="Prompt to provide context for the annotation task",
|
| 141 |
+
),
|
| 142 |
+
InputParam(
|
| 143 |
+
"annotation_output_type",
|
| 144 |
+
type_hint=str,
|
| 145 |
+
default="mask_image",
|
| 146 |
+
description="Output type: 'mask_image', 'mask_overlay', or 'bounding_box'",
|
| 147 |
+
),
|
| 148 |
+
]
|
| 149 |
+
|
| 150 |
+
@property
|
| 151 |
+
def intermediate_outputs(self) -> List[OutputParam]:
|
| 152 |
+
return [
|
| 153 |
+
OutputParam(
|
| 154 |
+
"mask_image",
|
| 155 |
+
type_hint=Image.Image,
|
| 156 |
+
description="Inpainting mask for the input image",
|
| 157 |
+
),
|
| 158 |
+
OutputParam(
|
| 159 |
+
"annotations",
|
| 160 |
+
type_hint=dict,
|
| 161 |
+
description="Raw annotation predictions",
|
| 162 |
+
),
|
| 163 |
+
OutputParam(
|
| 164 |
+
"image",
|
| 165 |
+
type_hint=Image.Image,
|
| 166 |
+
description="Annotated image",
|
| 167 |
+
),
|
| 168 |
+
]
|
| 169 |
+
```
|
| 170 |
+
|
| 171 |
+
### Implement the `__call__` method
|
| 172 |
+
|
| 173 |
+
The `__call__` method contains the block's logic. Access inputs via `block_state`, run your computation, and set outputs back to `block_state`.
|
| 174 |
+
|
| 175 |
+
```python
|
| 176 |
+
import torch
|
| 177 |
+
from diffusers.modular_pipelines import PipelineState
|
| 178 |
+
|
| 179 |
+
|
| 180 |
+
class Florence2ImageAnnotatorBlock(ModularPipelineBlocks):
|
| 181 |
+
|
| 182 |
+
# ... expected_components, inputs, intermediate_outputs from above ...
|
| 183 |
+
|
| 184 |
+
@torch.no_grad()
|
| 185 |
+
def __call__(self, components, state: PipelineState) -> PipelineState:
|
| 186 |
+
block_state = self.get_block_state(state)
|
| 187 |
+
|
| 188 |
+
images, annotation_task_prompt = self.prepare_inputs(
|
| 189 |
+
block_state.image, block_state.annotation_prompt
|
| 190 |
+
)
|
| 191 |
+
task = block_state.annotation_task
|
| 192 |
+
fill = block_state.fill
|
| 193 |
+
|
| 194 |
+
annotations = self.get_annotations(
|
| 195 |
+
components, images, annotation_task_prompt, task
|
| 196 |
+
)
|
| 197 |
+
block_state.annotations = annotations
|
| 198 |
+
if block_state.annotation_output_type == "mask_image":
|
| 199 |
+
block_state.mask_image = self.prepare_mask(images, annotations)
|
| 200 |
+
else:
|
| 201 |
+
block_state.mask_image = None
|
| 202 |
+
|
| 203 |
+
if block_state.annotation_output_type == "mask_overlay":
|
| 204 |
+
block_state.image = self.prepare_mask(images, annotations, overlay=True, fill=fill)
|
| 205 |
+
|
| 206 |
+
elif block_state.annotation_output_type == "bounding_box":
|
| 207 |
+
block_state.image = self.prepare_bounding_boxes(images, annotations)
|
| 208 |
+
|
| 209 |
+
self.set_block_state(state, block_state)
|
| 210 |
+
|
| 211 |
+
return components, state
|
| 212 |
+
|
| 213 |
+
# Helper methods for mask/bounding box generation...
|
| 214 |
+
```
|
| 215 |
+
|
| 216 |
+
> [!TIP]
|
| 217 |
+
> See the complete implementation at [diffusers/Florence2-image-Annotator](https://huggingface.co/diffusers/Florence2-image-Annotator).
|
| 218 |
+
|
| 219 |
+
## Using Custom Blocks
|
| 220 |
+
|
| 221 |
+
Load a custom block with [`~ModularPipeline.from_pretrained`] and set `trust_remote_code=True`.
|
| 222 |
+
|
| 223 |
+
```py
|
| 224 |
+
import torch
|
| 225 |
+
from diffusers import ModularPipeline
|
| 226 |
+
from diffusers.utils import load_image
|
| 227 |
+
|
| 228 |
+
# Load the Florence-2 annotator pipeline
|
| 229 |
+
image_annotator = ModularPipeline.from_pretrained(
|
| 230 |
+
"diffusers/Florence2-image-Annotator",
|
| 231 |
+
trust_remote_code=True
|
| 232 |
+
)
|
| 233 |
+
|
| 234 |
+
# Check the docstring to see inputs/outputs
|
| 235 |
+
print(image_annotator.blocks.doc)
|
| 236 |
+
```
|
| 237 |
+
|
| 238 |
+
Use the block to generate a mask:
|
| 239 |
+
|
| 240 |
+
```python
|
| 241 |
+
image_annotator.load_components(torch_dtype=torch.bfloat16)
|
| 242 |
+
image_annotator.to("cuda")
|
| 243 |
+
|
| 244 |
+
image = load_image("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/tasks/car.jpg")
|
| 245 |
+
image = image.resize((1024, 1024))
|
| 246 |
+
prompt = ["A red car"]
|
| 247 |
+
annotation_task = "<REFERRING_EXPRESSION_SEGMENTATION>"
|
| 248 |
+
annotation_prompt = ["the car"]
|
| 249 |
+
|
| 250 |
+
mask_image = image_annotator_node(
|
| 251 |
+
prompt=prompt,
|
| 252 |
+
image=image,
|
| 253 |
+
annotation_task=annotation_task,
|
| 254 |
+
annotation_prompt=annotation_prompt,
|
| 255 |
+
annotation_output_type="mask_image",
|
| 256 |
+
).images
|
| 257 |
+
mask_image[0].save("car-mask.png")
|
| 258 |
+
```
|
| 259 |
+
|
| 260 |
+
Compose it with other blocks to create a new pipeline:
|
| 261 |
+
|
| 262 |
+
```python
|
| 263 |
+
# Get the annotator block
|
| 264 |
+
annotator_block = image_annotator.blocks
|
| 265 |
+
|
| 266 |
+
# Get an inpainting workflow and insert the annotator at the beginning
|
| 267 |
+
inpaint_blocks = ModularPipeline.from_pretrained("Qwen/Qwen-Image").blocks.get_workflow("inpainting")
|
| 268 |
+
inpaint_blocks.sub_blocks.insert("image_annotator", annotator_block, 0)
|
| 269 |
+
|
| 270 |
+
# Initialize the combined pipeline
|
| 271 |
+
pipe = inpaint_blocks.init_pipeline()
|
| 272 |
+
pipe.load_components(torch_dtype=torch.float16, device="cuda")
|
| 273 |
+
|
| 274 |
+
# Now the pipeline automatically generates masks from prompts
|
| 275 |
+
output = pipe(
|
| 276 |
+
prompt=prompt,
|
| 277 |
+
image=image,
|
| 278 |
+
annotation_task=annotation_task,
|
| 279 |
+
annotation_prompt=annotation_prompt,
|
| 280 |
+
annotation_output_type="mask_image",
|
| 281 |
+
num_inference_steps=35,
|
| 282 |
+
guidance_scale=7.5,
|
| 283 |
+
strength=0.95,
|
| 284 |
+
output="images"
|
| 285 |
+
)
|
| 286 |
+
output[0].save("florence-inpainting.png")
|
| 287 |
+
```
|
| 288 |
+
|
| 289 |
+
## Editing custom blocks
|
| 290 |
+
|
| 291 |
+
Edit custom blocks by downloading it locally. This is the same workflow as the [Quick Start with Template](#quick-start-with-template), but starting from an existing block instead of the template.
|
| 292 |
+
|
| 293 |
+
Use the `local_dir` argument to download a custom block to a specific folder:
|
| 294 |
+
|
| 295 |
+
```python
|
| 296 |
+
from diffusers import ModularPipelineBlocks
|
| 297 |
+
|
| 298 |
+
# Download to a local folder for editing
|
| 299 |
+
annotator_block = ModularPipelineBlocks.from_pretrained(
|
| 300 |
+
"diffusers/Florence2-image-Annotator",
|
| 301 |
+
trust_remote_code=True,
|
| 302 |
+
local_dir="./my-florence-block"
|
| 303 |
+
)
|
| 304 |
+
```
|
| 305 |
+
|
| 306 |
+
Any changes made to the block files in this folder will be reflected when you load the block again. When you're ready to share your changes, upload to a new repository:
|
| 307 |
+
|
| 308 |
+
```python
|
| 309 |
+
pipeline = annotator_block.init_pipeline()
|
| 310 |
+
pipeline.save_pretrained("./my-florence-block", repo_id="your-username/my-custom-florence", push_to_hub=True)
|
| 311 |
+
```
|
| 312 |
+
|
| 313 |
+
## Next Steps
|
| 314 |
+
|
| 315 |
+
<hfoptions id="next">
|
| 316 |
+
<hfoption id="Learn block types">
|
| 317 |
+
|
| 318 |
+
This guide covered creating a single custom block. Learn how to compose multiple blocks together:
|
| 319 |
+
|
| 320 |
+
- [SequentialPipelineBlocks](./sequential_pipeline_blocks): Chain blocks to execute in sequence
|
| 321 |
+
- [ConditionalPipelineBlocks](./auto_pipeline_blocks): Create conditional blocks that select different execution paths
|
| 322 |
+
- [LoopSequentialPipelineBlocks](./loop_sequential_pipeline_blocks): Define an iterative workflows like the denoising loop
|
| 323 |
+
|
| 324 |
+
</hfoption>
|
| 325 |
+
<hfoption id="Use in Mellon">
|
| 326 |
+
|
| 327 |
+
Make your custom block work with Mellon's visual interface. See the [Mellon Custom Blocks](./mellon) guide.
|
| 328 |
+
|
| 329 |
+
</hfoption>
|
| 330 |
+
<hfoption id="Explore existing blocks">
|
| 331 |
+
|
| 332 |
+
Browse the [Modular Diffusers Custom Blocks](https://huggingface.co/collections/diffusers/modular-diffusers-custom-blocks) collection for inspiration and ready-to-use blocks.
|
| 333 |
+
|
| 334 |
+
</hfoption>
|
| 335 |
+
</hfoptions>
|
tasks/tasksmith-d977e5ab6579/environment/source/docs/source/en/modular_diffusers/guiders.md
ADDED
|
@@ -0,0 +1,161 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Guiders
|
| 14 |
+
|
| 15 |
+
[Classifier-free guidance](https://huggingface.co/papers/2207.12598) steers model generation that better match a prompt and is commonly used to improve generation quality, control, and adherence to prompts. There are different types of guidance methods, and in Diffusers, they are known as *guiders*. Like blocks, it is easy to switch and use different guiders for different use cases without rewriting the pipeline.
|
| 16 |
+
|
| 17 |
+
This guide will show you how to switch guiders, adjust guider parameters, and load and share them to the Hub.
|
| 18 |
+
|
| 19 |
+
## Switching guiders
|
| 20 |
+
|
| 21 |
+
[`ClassifierFreeGuidance`] is the default guider and created when a pipeline is initialized with [`~ModularPipelineBlocks.init_pipeline`]. It is created by `from_config` which means it doesn't require loading specifications from a modular repository. A guider won't be listed in `modular_model_index.json`.
|
| 22 |
+
|
| 23 |
+
Use [`~ModularPipeline.get_component_spec`] to inspect a guider.
|
| 24 |
+
|
| 25 |
+
```py
|
| 26 |
+
t2i_pipeline.get_component_spec("guider")
|
| 27 |
+
ComponentSpec(name='guider', type_hint=<class 'diffusers.guiders.classifier_free_guidance.ClassifierFreeGuidance'>, description=None, config=FrozenDict([('guidance_scale', 7.5), ('guidance_rescale', 0.0), ('use_original_formulation', False), ('start', 0.0), ('stop', 1.0), ('_use_default_values', ['start', 'guidance_rescale', 'stop', 'use_original_formulation'])]), repo=None, subfolder=None, variant=None, revision=None, default_creation_method='from_config')
|
| 28 |
+
```
|
| 29 |
+
|
| 30 |
+
Switch to a different guider by passing the new guider to [`~ModularPipeline.update_components`].
|
| 31 |
+
|
| 32 |
+
> [!TIP]
|
| 33 |
+
> Changing guiders will return text letting you know you're changing the guider type.
|
| 34 |
+
> ```bash
|
| 35 |
+
> ModularPipeline.update_components: adding guider with new type: PerturbedAttentionGuidance, previous type: ClassifierFreeGuidance
|
| 36 |
+
> ```
|
| 37 |
+
|
| 38 |
+
```py
|
| 39 |
+
from diffusers import LayerSkipConfig, PerturbedAttentionGuidance
|
| 40 |
+
|
| 41 |
+
config = LayerSkipConfig(indices=[2, 9], fqn="mid_block.attentions.0.transformer_blocks", skip_attention=False, skip_attention_scores=True, skip_ff=False)
|
| 42 |
+
guider = PerturbedAttentionGuidance(
|
| 43 |
+
guidance_scale=5.0, perturbed_guidance_scale=2.5, perturbed_guidance_config=config
|
| 44 |
+
)
|
| 45 |
+
t2i_pipeline.update_components(guider=guider)
|
| 46 |
+
```
|
| 47 |
+
|
| 48 |
+
Use [`~ModularPipeline.get_component_spec`] again to verify the guider type is different.
|
| 49 |
+
|
| 50 |
+
```py
|
| 51 |
+
t2i_pipeline.get_component_spec("guider")
|
| 52 |
+
ComponentSpec(name='guider', type_hint=<class 'diffusers.guiders.perturbed_attention_guidance.PerturbedAttentionGuidance'>, description=None, config=FrozenDict([('guidance_scale', 5.0), ('perturbed_guidance_scale', 2.5), ('perturbed_guidance_start', 0.01), ('perturbed_guidance_stop', 0.2), ('perturbed_guidance_layers', None), ('perturbed_guidance_config', LayerSkipConfig(indices=[2, 9], fqn='mid_block.attentions.0.transformer_blocks', skip_attention=False, skip_attention_scores=True, skip_ff=False, dropout=1.0)), ('guidance_rescale', 0.0), ('use_original_formulation', False), ('start', 0.0), ('stop', 1.0), ('_use_default_values', ['perturbed_guidance_start', 'use_original_formulation', 'perturbed_guidance_layers', 'stop', 'start', 'guidance_rescale', 'perturbed_guidance_stop']), ('_class_name', 'PerturbedAttentionGuidance'), ('_diffusers_version', '0.35.0.dev0')]), repo=None, subfolder=None, variant=None, revision=None, default_creation_method='from_config')
|
| 53 |
+
```
|
| 54 |
+
|
| 55 |
+
## Loading custom guiders
|
| 56 |
+
|
| 57 |
+
Guiders that are already saved on the Hub with a `modular_model_index.json` file are considered a `from_pretrained` component now instead of a `from_config` component.
|
| 58 |
+
|
| 59 |
+
```json
|
| 60 |
+
{
|
| 61 |
+
"guider": [
|
| 62 |
+
null,
|
| 63 |
+
null,
|
| 64 |
+
{
|
| 65 |
+
"repo": "YiYiXu/modular-loader-t2i-guider",
|
| 66 |
+
"revision": null,
|
| 67 |
+
"subfolder": "pag_guider",
|
| 68 |
+
"type_hint": [
|
| 69 |
+
"diffusers",
|
| 70 |
+
"PerturbedAttentionGuidance"
|
| 71 |
+
],
|
| 72 |
+
"variant": null
|
| 73 |
+
}
|
| 74 |
+
]
|
| 75 |
+
}
|
| 76 |
+
```
|
| 77 |
+
|
| 78 |
+
The guider is only created after calling [`~ModularPipeline.load_components`] based on the loading specification in `modular_model_index.json`.
|
| 79 |
+
|
| 80 |
+
```py
|
| 81 |
+
t2i_pipeline = t2i_blocks.init_pipeline("YiYiXu/modular-doc-guider")
|
| 82 |
+
# not created during init
|
| 83 |
+
assert t2i_pipeline.guider is None
|
| 84 |
+
t2i_pipeline.load_components()
|
| 85 |
+
# loaded as PAG guider
|
| 86 |
+
t2i_pipeline.guider
|
| 87 |
+
```
|
| 88 |
+
|
| 89 |
+
|
| 90 |
+
## Changing guider parameters
|
| 91 |
+
|
| 92 |
+
The guider parameters can be adjusted with the [`~ComponentSpec.create`] method and [`~ModularPipeline.update_components`]. The example below changes the `guidance_scale` value.
|
| 93 |
+
|
| 94 |
+
|
| 95 |
+
```py
|
| 96 |
+
guider_spec = t2i_pipeline.get_component_spec("guider")
|
| 97 |
+
guider = guider_spec.create(guidance_scale=10)
|
| 98 |
+
t2i_pipeline.update_components(guider=guider)
|
| 99 |
+
```
|
| 100 |
+
|
| 101 |
+
## Uploading custom guiders
|
| 102 |
+
|
| 103 |
+
Call the [`~utils.PushToHubMixin.push_to_hub`] method on a custom guider to share it to the Hub.
|
| 104 |
+
|
| 105 |
+
```py
|
| 106 |
+
guider.push_to_hub("YiYiXu/modular-loader-t2i-guider", subfolder="pag_guider")
|
| 107 |
+
```
|
| 108 |
+
|
| 109 |
+
To make this guider available to the pipeline, either modify the `modular_model_index.json` file or use the [`~ModularPipeline.update_components`] method.
|
| 110 |
+
|
| 111 |
+
<hfoptions id="upload">
|
| 112 |
+
<hfoption id="modular_model_index.json">
|
| 113 |
+
|
| 114 |
+
Edit the `modular_model_index.json` file and add a loading specification for the guider by pointing to a folder containing the guider config.
|
| 115 |
+
|
| 116 |
+
```json
|
| 117 |
+
{
|
| 118 |
+
"guider": [
|
| 119 |
+
"diffusers",
|
| 120 |
+
"PerturbedAttentionGuidance",
|
| 121 |
+
{
|
| 122 |
+
"repo": "YiYiXu/modular-loader-t2i-guider",
|
| 123 |
+
"revision": null,
|
| 124 |
+
"subfolder": "pag_guider",
|
| 125 |
+
"type_hint": [
|
| 126 |
+
"diffusers",
|
| 127 |
+
"PerturbedAttentionGuidance"
|
| 128 |
+
],
|
| 129 |
+
"variant": null
|
| 130 |
+
}
|
| 131 |
+
],
|
| 132 |
+
```
|
| 133 |
+
|
| 134 |
+
</hfoption>
|
| 135 |
+
<hfoption id="update_components">
|
| 136 |
+
|
| 137 |
+
Change the [`~ComponentSpec.default_creation_method`] to `from_pretrained` and use [`~ModularPipeline.update_components`] to update the guider and component specifications as well as the pipeline config.
|
| 138 |
+
|
| 139 |
+
> [!TIP]
|
| 140 |
+
> Changing the creation method will return text letting you know you're changing the creation type to `from_pretrained`.
|
| 141 |
+
> ```bash
|
| 142 |
+
> ModularPipeline.update_components: changing the default_creation_method of guider from from_config to from_pretrained.
|
| 143 |
+
> ```
|
| 144 |
+
|
| 145 |
+
```py
|
| 146 |
+
guider_spec = t2i_pipeline.get_component_spec("guider")
|
| 147 |
+
guider_spec.default_creation_method="from_pretrained"
|
| 148 |
+
guider_spec.pretrained_model_name_or_path="YiYiXu/modular-loader-t2i-guider"
|
| 149 |
+
guider_spec.subfolder="pag_guider"
|
| 150 |
+
pag_guider = guider_spec.load()
|
| 151 |
+
t2i_pipeline.update_components(guider=pag_guider)
|
| 152 |
+
```
|
| 153 |
+
|
| 154 |
+
To make it the default guider for a pipeline, call [`~utils.PushToHubMixin.push_to_hub`]. This is an optional step and not necessary if you are only experimenting locally.
|
| 155 |
+
|
| 156 |
+
```py
|
| 157 |
+
t2i_pipeline.push_to_hub("YiYiXu/modular-doc-guider")
|
| 158 |
+
```
|
| 159 |
+
|
| 160 |
+
</hfoption>
|
| 161 |
+
</hfoptions>
|