


Stage Harbor release files 30501-31000
Browse filesThis view is limited to 50 files because it contains too many changes. See raw diff
- tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/using-diffusers/text-img2vid.md +562 -0
- tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/using-diffusers/textual_inversion_inference.md +65 -0
- tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/using-diffusers/unconditional_image_generation.md +55 -0
- tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/using-diffusers/weighted_prompts.md +435 -0
- tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/using-diffusers/write_own_pipeline.md +293 -0
- tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ja/_toctree.yml +16 -0
- tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ja/index.md +48 -0
- tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ja/installation.md +145 -0
- tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ja/quicktour.md +316 -0
- tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ja/stable_diffusion.md +260 -0
- tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ja/tutorials/autopipeline.md +168 -0
- tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ja/tutorials/tutorial_overview.md +23 -0
- tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/_toctree.yml +200 -0
- tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/api/pipelines/stable_diffusion/stable_diffusion_xl.md +400 -0
- tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/conceptual/contribution.md +511 -0
- tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/conceptual/ethical_guidelines.md +64 -0
- tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/conceptual/evaluation.md +554 -0
- tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/conceptual/philosophy.md +103 -0
- tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/in_translation.md +16 -0
- tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/index.md +49 -0
- tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/installation.md +142 -0
- tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/optimization/coreml.md +168 -0
- tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/optimization/fp16.md +410 -0
- tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/optimization/habana.md +71 -0
- tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/optimization/mps.md +71 -0
- tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/optimization/onnx.md +65 -0
- tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/optimization/open_vino.md +39 -0
- tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/optimization/tome.md +121 -0
- tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/optimization/torch2.0.md +445 -0
- tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/optimization/xformers.md +36 -0
- tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/quicktour.md +313 -0
- tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/stable_diffusion.md +279 -0
- tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/training/adapt_a_model.md +54 -0
- tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/training/controlnet.md +325 -0
- tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/training/create_dataset.md +98 -0
- tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/training/custom_diffusion.md +300 -0
- tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/training/distributed_inference.md +92 -0
- tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/training/dreambooth.md +474 -0
- tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/training/instructpix2pix.md +211 -0
- tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/training/lora.md +128 -0
- tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/training/overview.md +73 -0
- tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/training/text2image.md +224 -0
- tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/training/text_inversion.md +275 -0
- tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/training/unconditional_training.md +144 -0
- tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/tutorials/basic_training.md +402 -0
- tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/tutorials/tutorial_overview.md +23 -0
- tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/using-diffusers/conditional_image_generation.md +60 -0
- tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/using-diffusers/controlling_generation.md +226 -0
- tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/using-diffusers/custom_pipeline_overview.md +56 -0
- tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/using-diffusers/depth2img.md +57 -0
tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/using-diffusers/text-img2vid.md
ADDED
|
@@ -0,0 +1,562 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2024 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Video generation
|
| 14 |
+
|
| 15 |
+
Video generation models include a temporal dimension to bring images, or frames, together to create a video. These models are trained on large-scale datasets of high-quality text-video pairs to learn how to combine the modalities to ensure the generated video is coherent and realistic.
|
| 16 |
+
|
| 17 |
+
[Explore](https://huggingface.co/models?other=video-generation) some of the more popular open-source video generation models available from Diffusers below.
|
| 18 |
+
|
| 19 |
+
<hfoptions id="popular-models">
|
| 20 |
+
<hfoption id="CogVideoX">
|
| 21 |
+
|
| 22 |
+
[CogVideoX](https://huggingface.co/collections/THUDM/cogvideo-66c08e62f1685a3ade464cce) uses a 3D causal Variational Autoencoder (VAE) to compress videos along the spatial and temporal dimensions, and it includes a stack of expert transformer blocks with a 3D full attention mechanism to better capture visual, semantic, and motion information in the data.
|
| 23 |
+
|
| 24 |
+
The CogVideoX family also includes models capable of generating videos from images and videos in addition to text. The image-to-video models are indicated by **I2V** in the checkpoint name, and they should be used with the [`CogVideoXImageToVideoPipeline`]. The regular checkpoints support video-to-video through the [`CogVideoXVideoToVideoPipeline`].
|
| 25 |
+
|
| 26 |
+
The example below demonstrates how to generate a video from an image and text prompt with [THUDM/CogVideoX-5b-I2V](https://huggingface.co/THUDM/CogVideoX-5b-I2V).
|
| 27 |
+
|
| 28 |
+
```py
|
| 29 |
+
import torch
|
| 30 |
+
from diffusers import CogVideoXImageToVideoPipeline
|
| 31 |
+
from diffusers.utils import export_to_video, load_image
|
| 32 |
+
|
| 33 |
+
prompt = "A vast, shimmering ocean flows gracefully under a twilight sky, its waves undulating in a mesmerizing dance of blues and greens. The surface glints with the last rays of the setting sun, casting golden highlights that ripple across the water. Seagulls soar above, their cries blending with the gentle roar of the waves. The horizon stretches infinitely, where the ocean meets the sky in a seamless blend of hues. Close-ups reveal the intricate patterns of the waves, capturing the fluidity and dynamic beauty of the sea in motion."
|
| 34 |
+
image = load_image(image="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/cogvideox/cogvideox_rocket.png")
|
| 35 |
+
pipe = CogVideoXImageToVideoPipeline.from_pretrained(
|
| 36 |
+
"THUDM/CogVideoX-5b-I2V",
|
| 37 |
+
torch_dtype=torch.bfloat16
|
| 38 |
+
)
|
| 39 |
+
|
| 40 |
+
# reduce memory requirements
|
| 41 |
+
pipe.vae.enable_tiling()
|
| 42 |
+
pipe.vae.enable_slicing()
|
| 43 |
+
|
| 44 |
+
video = pipe(
|
| 45 |
+
prompt=prompt,
|
| 46 |
+
image=image,
|
| 47 |
+
num_videos_per_prompt=1,
|
| 48 |
+
num_inference_steps=50,
|
| 49 |
+
num_frames=49,
|
| 50 |
+
guidance_scale=6,
|
| 51 |
+
generator=torch.Generator(device="cuda").manual_seed(42),
|
| 52 |
+
).frames[0]
|
| 53 |
+
export_to_video(video, "output.mp4", fps=8)
|
| 54 |
+
```
|
| 55 |
+
|
| 56 |
+
<div class="flex gap-4">
|
| 57 |
+
<div>
|
| 58 |
+
<img class="rounded-xl" src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/cogvideox/cogvideox_rocket.png"/>
|
| 59 |
+
<figcaption class="mt-2 text-center text-sm text-gray-500">initial image</figcaption>
|
| 60 |
+
</div>
|
| 61 |
+
<div>
|
| 62 |
+
<img class="rounded-xl" src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/cogvideox/cogvideox_outrocket.gif"/>
|
| 63 |
+
<figcaption class="mt-2 text-center text-sm text-gray-500">generated video</figcaption>
|
| 64 |
+
</div>
|
| 65 |
+
</div>
|
| 66 |
+
|
| 67 |
+
</hfoption>
|
| 68 |
+
<hfoption id="HunyuanVideo">
|
| 69 |
+
|
| 70 |
+
> [!TIP]
|
| 71 |
+
> HunyuanVideo is a 13B parameter model and requires a lot of memory. Refer to the HunyuanVideo [Quantization](../api/pipelines/hunyuan_video#quantization) guide to learn how to quantize the model. CogVideoX and LTX-Video are more lightweight options that can still generate high-quality videos.
|
| 72 |
+
|
| 73 |
+
[HunyuanVideo](https://huggingface.co/tencent/HunyuanVideo) features a dual-stream to single-stream diffusion transformer (DiT) for learning video and text tokens separately, and then subsequently concatenating the video and text tokens to combine their information. A single multimodal large language model (MLLM) serves as the text encoder, and videos are also spatio-temporally compressed with a 3D causal VAE.
|
| 74 |
+
|
| 75 |
+
```py
|
| 76 |
+
import torch
|
| 77 |
+
from diffusers import HunyuanVideoPipeline, HunyuanVideoTransformer3DModel
|
| 78 |
+
from diffusers.utils import export_to_video
|
| 79 |
+
|
| 80 |
+
transformer = HunyuanVideoTransformer3DModel.from_pretrained(
|
| 81 |
+
"hunyuanvideo-community/HunyuanVideo", subfolder="transformer", torch_dtype=torch.bfloat16
|
| 82 |
+
)
|
| 83 |
+
pipe = HunyuanVideoPipeline.from_pretrained(
|
| 84 |
+
"hunyuanvideo-community/HunyuanVideo", transformer=transformer, torch_dtype=torch.float16
|
| 85 |
+
)
|
| 86 |
+
|
| 87 |
+
# reduce memory requirements
|
| 88 |
+
pipe.vae.enable_tiling()
|
| 89 |
+
pipe.to("cuda")
|
| 90 |
+
|
| 91 |
+
video = pipe(
|
| 92 |
+
prompt="A cat walks on the grass, realistic",
|
| 93 |
+
height=320,
|
| 94 |
+
width=512,
|
| 95 |
+
num_frames=61,
|
| 96 |
+
num_inference_steps=30,
|
| 97 |
+
).frames[0]
|
| 98 |
+
export_to_video(video, "output.mp4", fps=15)
|
| 99 |
+
```
|
| 100 |
+
|
| 101 |
+
<div class="flex justify-center">
|
| 102 |
+
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/hunyuan-video-output.gif"/>
|
| 103 |
+
</div>
|
| 104 |
+
|
| 105 |
+
</hfoption>
|
| 106 |
+
<hfoption id="LTX-Video">
|
| 107 |
+
|
| 108 |
+
[LTX-Video (LTXV)](https://huggingface.co/Lightricks/LTX-Video) is a diffusion transformer (DiT) with a focus on speed. It generates 768x512 resolution videos at 24 frames per second (fps), enabling near real-time generation of high-quality videos. LTXV is relatively lightweight compared to other modern video generation models, making it possible to run on consumer GPUs.
|
| 109 |
+
|
| 110 |
+
```py
|
| 111 |
+
import torch
|
| 112 |
+
from diffusers import LTXPipeline
|
| 113 |
+
from diffusers.utils import export_to_video
|
| 114 |
+
|
| 115 |
+
pipe = LTXPipeline.from_pretrained("Lightricks/LTX-Video", torch_dtype=torch.bfloat16).to("cuda")
|
| 116 |
+
|
| 117 |
+
prompt = "A man walks towards a window, looks out, and then turns around. He has short, dark hair, dark skin, and is wearing a brown coat over a red and gray scarf. He walks from left to right towards a window, his gaze fixed on something outside. The camera follows him from behind at a medium distance. The room is brightly lit, with white walls and a large window covered by a white curtain. As he approaches the window, he turns his head slightly to the left, then back to the right. He then turns his entire body to the right, facing the window. The camera remains stationary as he stands in front of the window. The scene is captured in real-life footage."
|
| 118 |
+
video = pipe(
|
| 119 |
+
prompt=prompt,
|
| 120 |
+
width=704,
|
| 121 |
+
height=480,
|
| 122 |
+
num_frames=161,
|
| 123 |
+
num_inference_steps=50,
|
| 124 |
+
).frames[0]
|
| 125 |
+
export_to_video(video, "output.mp4", fps=24)
|
| 126 |
+
```
|
| 127 |
+
|
| 128 |
+
<div class="flex justify-center">
|
| 129 |
+
<img src="https://huggingface.co/Lightricks/LTX-Video/resolve/main/media/ltx-video_example_00014.gif"/>
|
| 130 |
+
</div>
|
| 131 |
+
|
| 132 |
+
</hfoption>
|
| 133 |
+
<hfoption id="Mochi-1">
|
| 134 |
+
|
| 135 |
+
> [!TIP]
|
| 136 |
+
> Mochi-1 is a 10B parameter model and requires a lot of memory. Refer to the Mochi [Quantization](../api/pipelines/mochi#quantization) guide to learn how to quantize the model. CogVideoX and LTX-Video are more lightweight options that can still generate high-quality videos.
|
| 137 |
+
|
| 138 |
+
[Mochi-1](https://huggingface.co/genmo/mochi-1-preview) introduces the Asymmetric Diffusion Transformer (AsymmDiT) and Asymmetric Variational Autoencoder (AsymmVAE) to reduces memory requirements. AsymmVAE causally compresses videos 128x to improve memory efficiency, and AsymmDiT jointly attends to the compressed video tokens and user text tokens. This model is noted for generating videos with high-quality motion dynamics and strong prompt adherence.
|
| 139 |
+
|
| 140 |
+
```py
|
| 141 |
+
import torch
|
| 142 |
+
from diffusers import MochiPipeline
|
| 143 |
+
from diffusers.utils import export_to_video
|
| 144 |
+
|
| 145 |
+
pipe = MochiPipeline.from_pretrained("genmo/mochi-1-preview", variant="bf16", torch_dtype=torch.bfloat16)
|
| 146 |
+
|
| 147 |
+
# reduce memory requirements
|
| 148 |
+
pipe.enable_model_cpu_offload()
|
| 149 |
+
pipe.enable_vae_tiling()
|
| 150 |
+
|
| 151 |
+
prompt = "Close-up of a chameleon's eye, with its scaly skin changing color. Ultra high resolution 4k."
|
| 152 |
+
video = pipe(prompt, num_frames=84).frames[0]
|
| 153 |
+
export_to_video(video, "output.mp4", fps=30)
|
| 154 |
+
```
|
| 155 |
+
|
| 156 |
+
<div class="flex justify-center">
|
| 157 |
+
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/mochi-video-output.gif"/>
|
| 158 |
+
</div>
|
| 159 |
+
|
| 160 |
+
</hfoption>
|
| 161 |
+
<hfoption id="StableVideoDiffusion">
|
| 162 |
+
|
| 163 |
+
[StableVideoDiffusion (SVD)](https://huggingface.co/stabilityai/stable-video-diffusion-img2vid-xt) is based on the Stable Diffusion 2.1 model and it is trained on images, then low-resolution videos, and finally a smaller dataset of high-resolution videos. This model generates a short 2-4 second video from an initial image.
|
| 164 |
+
|
| 165 |
+
```py
|
| 166 |
+
import torch
|
| 167 |
+
from diffusers import StableVideoDiffusionPipeline
|
| 168 |
+
from diffusers.utils import load_image, export_to_video
|
| 169 |
+
|
| 170 |
+
pipeline = StableVideoDiffusionPipeline.from_pretrained(
|
| 171 |
+
"stabilityai/stable-video-diffusion-img2vid-xt", torch_dtype=torch.float16, variant="fp16"
|
| 172 |
+
)
|
| 173 |
+
|
| 174 |
+
# reduce memory requirements
|
| 175 |
+
pipeline.enable_model_cpu_offload()
|
| 176 |
+
|
| 177 |
+
image = load_image("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/svd/rocket.png")
|
| 178 |
+
image = image.resize((1024, 576))
|
| 179 |
+
|
| 180 |
+
generator = torch.manual_seed(42)
|
| 181 |
+
frames = pipeline(image, decode_chunk_size=8, generator=generator).frames[0]
|
| 182 |
+
export_to_video(frames, "generated.mp4", fps=7)
|
| 183 |
+
```
|
| 184 |
+
|
| 185 |
+
<div class="flex gap-4">
|
| 186 |
+
<div>
|
| 187 |
+
<img class="rounded-xl" src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/svd/rocket.png"/>
|
| 188 |
+
<figcaption class="mt-2 text-center text-sm text-gray-500">initial image</figcaption>
|
| 189 |
+
</div>
|
| 190 |
+
<div>
|
| 191 |
+
<img class="rounded-xl" src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/svd/output_rocket.gif"/>
|
| 192 |
+
<figcaption class="mt-2 text-center text-sm text-gray-500">generated video</figcaption>
|
| 193 |
+
</div>
|
| 194 |
+
</div>
|
| 195 |
+
|
| 196 |
+
</hfoption>
|
| 197 |
+
<hfoption id="AnimateDiff">
|
| 198 |
+
|
| 199 |
+
[AnimateDiff](https://huggingface.co/guoyww/animatediff) is an adapter model that inserts a motion module into a pretrained diffusion model to animate an image. The adapter is trained on video clips to learn motion which is used to condition the generation process to create a video. It is faster and easier to only train the adapter and it can be loaded into most diffusion models, effectively turning them into “video models”.
|
| 200 |
+
|
| 201 |
+
Load a `MotionAdapter` and pass it to the [`AnimateDiffPipeline`].
|
| 202 |
+
|
| 203 |
+
```py
|
| 204 |
+
import torch
|
| 205 |
+
from diffusers import AnimateDiffPipeline, DDIMScheduler, MotionAdapter
|
| 206 |
+
from diffusers.utils import export_to_gif
|
| 207 |
+
|
| 208 |
+
adapter = MotionAdapter.from_pretrained("guoyww/animatediff-motion-adapter-v1-5-2", torch_dtype=torch.float16)
|
| 209 |
+
pipeline = AnimateDiffPipeline.from_pretrained("emilianJR/epiCRealism", motion_adapter=adapter, torch_dtype=torch.float16)
|
| 210 |
+
scheduler = DDIMScheduler.from_pretrained(
|
| 211 |
+
"emilianJR/epiCRealism",
|
| 212 |
+
subfolder="scheduler",
|
| 213 |
+
clip_sample=False,
|
| 214 |
+
timestep_spacing="linspace",
|
| 215 |
+
beta_schedule="linear",
|
| 216 |
+
steps_offset=1,
|
| 217 |
+
)
|
| 218 |
+
pipeline.scheduler = scheduler
|
| 219 |
+
|
| 220 |
+
# reduce memory requirements
|
| 221 |
+
pipeline.enable_vae_slicing()
|
| 222 |
+
pipeline.enable_model_cpu_offload()
|
| 223 |
+
|
| 224 |
+
output = pipeline(
|
| 225 |
+
prompt="A space rocket with trails of smoke behind it launching into space from the desert, 4k, high resolution",
|
| 226 |
+
negative_prompt="bad quality, worse quality, low resolution",
|
| 227 |
+
num_frames=16,
|
| 228 |
+
guidance_scale=7.5,
|
| 229 |
+
num_inference_steps=50,
|
| 230 |
+
generator=torch.Generator("cpu").manual_seed(49),
|
| 231 |
+
)
|
| 232 |
+
frames = output.frames[0]
|
| 233 |
+
export_to_gif(frames, "animation.gif")
|
| 234 |
+
```
|
| 235 |
+
|
| 236 |
+
<div class="flex justify-center">
|
| 237 |
+
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/animatediff.gif"/>
|
| 238 |
+
</div>
|
| 239 |
+
|
| 240 |
+
</hfoption>
|
| 241 |
+
</hfoptions>
|
| 242 |
+
|
| 243 |
+
## Configure model parameters
|
| 244 |
+
|
| 245 |
+
There are a few important parameters you can configure in the pipeline that'll affect the video generation process and quality. Let's take a closer look at what these parameters do and how changing them affects the output.
|
| 246 |
+
|
| 247 |
+
### Number of frames
|
| 248 |
+
|
| 249 |
+
The `num_frames` parameter determines how many video frames are generated per second. A frame is an image that is played in a sequence of other frames to create motion or a video. This affects video length because the pipeline generates a certain number of frames per second (check a pipeline's API reference for the default value). To increase the video duration, you'll need to increase the `num_frames` parameter.
|
| 250 |
+
|
| 251 |
+
```py
|
| 252 |
+
import torch
|
| 253 |
+
from diffusers import StableVideoDiffusionPipeline
|
| 254 |
+
from diffusers.utils import load_image, export_to_video
|
| 255 |
+
|
| 256 |
+
pipeline = StableVideoDiffusionPipeline.from_pretrained(
|
| 257 |
+
"stabilityai/stable-video-diffusion-img2vid", torch_dtype=torch.float16, variant="fp16"
|
| 258 |
+
)
|
| 259 |
+
pipeline.enable_model_cpu_offload()
|
| 260 |
+
|
| 261 |
+
image = load_image("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/svd/rocket.png")
|
| 262 |
+
image = image.resize((1024, 576))
|
| 263 |
+
|
| 264 |
+
generator = torch.manual_seed(42)
|
| 265 |
+
frames = pipeline(image, decode_chunk_size=8, generator=generator, num_frames=25).frames[0]
|
| 266 |
+
export_to_video(frames, "generated.mp4", fps=7)
|
| 267 |
+
```
|
| 268 |
+
|
| 269 |
+
<div class="flex gap-4">
|
| 270 |
+
<div>
|
| 271 |
+
<img class="rounded-xl" src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/num_frames_14.gif"/>
|
| 272 |
+
<figcaption class="mt-2 text-center text-sm text-gray-500">num_frames=14</figcaption>
|
| 273 |
+
</div>
|
| 274 |
+
<div>
|
| 275 |
+
<img class="rounded-xl" src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/num_frames_25.gif"/>
|
| 276 |
+
<figcaption class="mt-2 text-center text-sm text-gray-500">num_frames=25</figcaption>
|
| 277 |
+
</div>
|
| 278 |
+
</div>
|
| 279 |
+
|
| 280 |
+
### Guidance scale
|
| 281 |
+
|
| 282 |
+
The `guidance_scale` parameter controls how closely aligned the generated video and text prompt or initial image is. A higher `guidance_scale` value means your generated video is more aligned with the text prompt or initial image, while a lower `guidance_scale` value means your generated video is less aligned which could give the model more "creativity" to interpret the conditioning input.
|
| 283 |
+
|
| 284 |
+
<Tip>
|
| 285 |
+
|
| 286 |
+
SVD uses the `min_guidance_scale` and `max_guidance_scale` parameters for applying guidance to the first and last frames respectively.
|
| 287 |
+
|
| 288 |
+
</Tip>
|
| 289 |
+
|
| 290 |
+
```py
|
| 291 |
+
import torch
|
| 292 |
+
from diffusers import I2VGenXLPipeline
|
| 293 |
+
from diffusers.utils import export_to_gif, load_image
|
| 294 |
+
|
| 295 |
+
pipeline = I2VGenXLPipeline.from_pretrained("ali-vilab/i2vgen-xl", torch_dtype=torch.float16, variant="fp16")
|
| 296 |
+
pipeline.enable_model_cpu_offload()
|
| 297 |
+
|
| 298 |
+
image_url = "https://huggingface.co/datasets/diffusers/docs-images/resolve/main/i2vgen_xl_images/img_0009.png"
|
| 299 |
+
image = load_image(image_url).convert("RGB")
|
| 300 |
+
|
| 301 |
+
prompt = "Papers were floating in the air on a table in the library"
|
| 302 |
+
negative_prompt = "Distorted, discontinuous, Ugly, blurry, low resolution, motionless, static, disfigured, disconnected limbs, Ugly faces, incomplete arms"
|
| 303 |
+
generator = torch.manual_seed(0)
|
| 304 |
+
|
| 305 |
+
frames = pipeline(
|
| 306 |
+
prompt=prompt,
|
| 307 |
+
image=image,
|
| 308 |
+
num_inference_steps=50,
|
| 309 |
+
negative_prompt=negative_prompt,
|
| 310 |
+
guidance_scale=1.0,
|
| 311 |
+
generator=generator
|
| 312 |
+
).frames[0]
|
| 313 |
+
export_to_gif(frames, "i2v.gif")
|
| 314 |
+
```
|
| 315 |
+
|
| 316 |
+
<div class="flex gap-4">
|
| 317 |
+
<div>
|
| 318 |
+
<img class="rounded-xl" src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/i2vgen-xl-example.gif"/>
|
| 319 |
+
<figcaption class="mt-2 text-center text-sm text-gray-500">guidance_scale=9.0</figcaption>
|
| 320 |
+
</div>
|
| 321 |
+
<div>
|
| 322 |
+
<img class="rounded-xl" src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/guidance_scale_1.0.gif"/>
|
| 323 |
+
<figcaption class="mt-2 text-center text-sm text-gray-500">guidance_scale=1.0</figcaption>
|
| 324 |
+
</div>
|
| 325 |
+
</div>
|
| 326 |
+
|
| 327 |
+
### Negative prompt
|
| 328 |
+
|
| 329 |
+
A negative prompt deters the model from generating things you don’t want it to. This parameter is commonly used to improve overall generation quality by removing poor or bad features such as “low resolution” or “bad details”.
|
| 330 |
+
|
| 331 |
+
```py
|
| 332 |
+
import torch
|
| 333 |
+
from diffusers import AnimateDiffPipeline, DDIMScheduler, MotionAdapter
|
| 334 |
+
from diffusers.utils import export_to_gif
|
| 335 |
+
|
| 336 |
+
adapter = MotionAdapter.from_pretrained("guoyww/animatediff-motion-adapter-v1-5-2", torch_dtype=torch.float16)
|
| 337 |
+
|
| 338 |
+
pipeline = AnimateDiffPipeline.from_pretrained("emilianJR/epiCRealism", motion_adapter=adapter, torch_dtype=torch.float16)
|
| 339 |
+
scheduler = DDIMScheduler.from_pretrained(
|
| 340 |
+
"emilianJR/epiCRealism",
|
| 341 |
+
subfolder="scheduler",
|
| 342 |
+
clip_sample=False,
|
| 343 |
+
timestep_spacing="linspace",
|
| 344 |
+
beta_schedule="linear",
|
| 345 |
+
steps_offset=1,
|
| 346 |
+
)
|
| 347 |
+
pipeline.scheduler = scheduler
|
| 348 |
+
pipeline.enable_vae_slicing()
|
| 349 |
+
pipeline.enable_model_cpu_offload()
|
| 350 |
+
|
| 351 |
+
output = pipeline(
|
| 352 |
+
prompt="360 camera shot of a sushi roll in a restaurant",
|
| 353 |
+
negative_prompt="Distorted, discontinuous, ugly, blurry, low resolution, motionless, static",
|
| 354 |
+
num_frames=16,
|
| 355 |
+
guidance_scale=7.5,
|
| 356 |
+
num_inference_steps=50,
|
| 357 |
+
generator=torch.Generator("cpu").manual_seed(0),
|
| 358 |
+
)
|
| 359 |
+
frames = output.frames[0]
|
| 360 |
+
export_to_gif(frames, "animation.gif")
|
| 361 |
+
```
|
| 362 |
+
|
| 363 |
+
<div class="flex gap-4">
|
| 364 |
+
<div>
|
| 365 |
+
<img class="rounded-xl" src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/animatediff_no_neg.gif"/>
|
| 366 |
+
<figcaption class="mt-2 text-center text-sm text-gray-500">no negative prompt</figcaption>
|
| 367 |
+
</div>
|
| 368 |
+
<div>
|
| 369 |
+
<img class="rounded-xl" src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/animatediff_neg.gif"/>
|
| 370 |
+
<figcaption class="mt-2 text-center text-sm text-gray-500">negative prompt applied</figcaption>
|
| 371 |
+
</div>
|
| 372 |
+
</div>
|
| 373 |
+
|
| 374 |
+
### Model-specific parameters
|
| 375 |
+
|
| 376 |
+
There are some pipeline parameters that are unique to each model such as adjusting the motion in a video or adding noise to the initial image.
|
| 377 |
+
|
| 378 |
+
<hfoptions id="special-parameters">
|
| 379 |
+
<hfoption id="Stable Video Diffusion">
|
| 380 |
+
|
| 381 |
+
Stable Video Diffusion provides additional micro-conditioning for the frame rate with the `fps` parameter and for motion with the `motion_bucket_id` parameter. Together, these parameters allow for adjusting the amount of motion in the generated video.
|
| 382 |
+
|
| 383 |
+
There is also a `noise_aug_strength` parameter that increases the amount of noise added to the initial image. Varying this parameter affects how similar the generated video and initial image are. A higher `noise_aug_strength` also increases the amount of motion. To learn more, read the [Micro-conditioning](../using-diffusers/svd#micro-conditioning) guide.
|
| 384 |
+
|
| 385 |
+
</hfoption>
|
| 386 |
+
<hfoption id="Text2Video-Zero">
|
| 387 |
+
|
| 388 |
+
Text2Video-Zero computes the amount of motion to apply to each frame from randomly sampled latents. You can use the `motion_field_strength_x` and `motion_field_strength_y` parameters to control the amount of motion to apply to the x and y-axes of the video. The parameters `t0` and `t1` are the timesteps to apply motion to the latents.
|
| 389 |
+
|
| 390 |
+
</hfoption>
|
| 391 |
+
</hfoptions>
|
| 392 |
+
|
| 393 |
+
## Control video generation
|
| 394 |
+
|
| 395 |
+
Video generation can be controlled similar to how text-to-image, image-to-image, and inpainting can be controlled with a [`ControlNetModel`]. The only difference is you need to use the [`~pipelines.text_to_video_synthesis.pipeline_text_to_video_zero.CrossFrameAttnProcessor`] so each frame attends to the first frame.
|
| 396 |
+
|
| 397 |
+
### Text2Video-Zero
|
| 398 |
+
|
| 399 |
+
Text2Video-Zero video generation can be conditioned on pose and edge images for even greater control over a subject's motion in the generated video or to preserve the identity of a subject/object in the video. You can also use Text2Video-Zero with [InstructPix2Pix](../api/pipelines/pix2pix) for editing videos with text.
|
| 400 |
+
|
| 401 |
+
<hfoptions id="t2v-zero">
|
| 402 |
+
<hfoption id="pose control">
|
| 403 |
+
|
| 404 |
+
Start by downloading a video and extracting the pose images from it.
|
| 405 |
+
|
| 406 |
+
```py
|
| 407 |
+
from huggingface_hub import hf_hub_download
|
| 408 |
+
from PIL import Image
|
| 409 |
+
import imageio
|
| 410 |
+
|
| 411 |
+
filename = "__assets__/poses_skeleton_gifs/dance1_corr.mp4"
|
| 412 |
+
repo_id = "PAIR/Text2Video-Zero"
|
| 413 |
+
video_path = hf_hub_download(repo_type="space", repo_id=repo_id, filename=filename)
|
| 414 |
+
|
| 415 |
+
reader = imageio.get_reader(video_path, "ffmpeg")
|
| 416 |
+
frame_count = 8
|
| 417 |
+
pose_images = [Image.fromarray(reader.get_data(i)) for i in range(frame_count)]
|
| 418 |
+
```
|
| 419 |
+
|
| 420 |
+
Load a [`ControlNetModel`] for pose estimation and a checkpoint into the [`StableDiffusionControlNetPipeline`]. Then you'll use the [`~pipelines.text_to_video_synthesis.pipeline_text_to_video_zero.CrossFrameAttnProcessor`] for the UNet and ControlNet.
|
| 421 |
+
|
| 422 |
+
```py
|
| 423 |
+
import torch
|
| 424 |
+
from diffusers import StableDiffusionControlNetPipeline, ControlNetModel
|
| 425 |
+
from diffusers.pipelines.text_to_video_synthesis.pipeline_text_to_video_zero import CrossFrameAttnProcessor
|
| 426 |
+
|
| 427 |
+
model_id = "stable-diffusion-v1-5/stable-diffusion-v1-5"
|
| 428 |
+
controlnet = ControlNetModel.from_pretrained("lllyasviel/sd-controlnet-openpose", torch_dtype=torch.float16)
|
| 429 |
+
pipeline = StableDiffusionControlNetPipeline.from_pretrained(
|
| 430 |
+
model_id, controlnet=controlnet, torch_dtype=torch.float16
|
| 431 |
+
).to("cuda")
|
| 432 |
+
|
| 433 |
+
pipeline.unet.set_attn_processor(CrossFrameAttnProcessor(batch_size=2))
|
| 434 |
+
pipeline.controlnet.set_attn_processor(CrossFrameAttnProcessor(batch_size=2))
|
| 435 |
+
```
|
| 436 |
+
|
| 437 |
+
Fix the latents for all the frames, and then pass your prompt and extracted pose images to the model to generate a video.
|
| 438 |
+
|
| 439 |
+
```py
|
| 440 |
+
latents = torch.randn((1, 4, 64, 64), device="cuda", dtype=torch.float16).repeat(len(pose_images), 1, 1, 1)
|
| 441 |
+
|
| 442 |
+
prompt = "Darth Vader dancing in a desert"
|
| 443 |
+
result = pipeline(prompt=[prompt] * len(pose_images), image=pose_images, latents=latents).images
|
| 444 |
+
imageio.mimsave("video.mp4", result, fps=4)
|
| 445 |
+
```
|
| 446 |
+
|
| 447 |
+
</hfoption>
|
| 448 |
+
<hfoption id="edge control">
|
| 449 |
+
|
| 450 |
+
Download a video and extract the edges from it.
|
| 451 |
+
|
| 452 |
+
```py
|
| 453 |
+
from huggingface_hub import hf_hub_download
|
| 454 |
+
from PIL import Image
|
| 455 |
+
import imageio
|
| 456 |
+
|
| 457 |
+
filename = "__assets__/poses_skeleton_gifs/dance1_corr.mp4"
|
| 458 |
+
repo_id = "PAIR/Text2Video-Zero"
|
| 459 |
+
video_path = hf_hub_download(repo_type="space", repo_id=repo_id, filename=filename)
|
| 460 |
+
|
| 461 |
+
reader = imageio.get_reader(video_path, "ffmpeg")
|
| 462 |
+
frame_count = 8
|
| 463 |
+
pose_images = [Image.fromarray(reader.get_data(i)) for i in range(frame_count)]
|
| 464 |
+
```
|
| 465 |
+
|
| 466 |
+
Load a [`ControlNetModel`] for canny edge and a checkpoint into the [`StableDiffusionControlNetPipeline`]. Then you'll use the [`~pipelines.text_to_video_synthesis.pipeline_text_to_video_zero.CrossFrameAttnProcessor`] for the UNet and ControlNet.
|
| 467 |
+
|
| 468 |
+
```py
|
| 469 |
+
import torch
|
| 470 |
+
from diffusers import StableDiffusionControlNetPipeline, ControlNetModel
|
| 471 |
+
from diffusers.pipelines.text_to_video_synthesis.pipeline_text_to_video_zero import CrossFrameAttnProcessor
|
| 472 |
+
|
| 473 |
+
model_id = "stable-diffusion-v1-5/stable-diffusion-v1-5"
|
| 474 |
+
controlnet = ControlNetModel.from_pretrained("lllyasviel/sd-controlnet-canny", torch_dtype=torch.float16)
|
| 475 |
+
pipeline = StableDiffusionControlNetPipeline.from_pretrained(
|
| 476 |
+
model_id, controlnet=controlnet, torch_dtype=torch.float16
|
| 477 |
+
).to("cuda")
|
| 478 |
+
|
| 479 |
+
pipeline.unet.set_attn_processor(CrossFrameAttnProcessor(batch_size=2))
|
| 480 |
+
pipeline.controlnet.set_attn_processor(CrossFrameAttnProcessor(batch_size=2))
|
| 481 |
+
```
|
| 482 |
+
|
| 483 |
+
Fix the latents for all the frames, and then pass your prompt and extracted edge images to the model to generate a video.
|
| 484 |
+
|
| 485 |
+
```py
|
| 486 |
+
latents = torch.randn((1, 4, 64, 64), device="cuda", dtype=torch.float16).repeat(len(pose_images), 1, 1, 1)
|
| 487 |
+
|
| 488 |
+
prompt = "Darth Vader dancing in a desert"
|
| 489 |
+
result = pipeline(prompt=[prompt] * len(pose_images), image=pose_images, latents=latents).images
|
| 490 |
+
imageio.mimsave("video.mp4", result, fps=4)
|
| 491 |
+
```
|
| 492 |
+
|
| 493 |
+
</hfoption>
|
| 494 |
+
<hfoption id="InstructPix2Pix">
|
| 495 |
+
|
| 496 |
+
InstructPix2Pix allows you to use text to describe the changes you want to make to the video. Start by downloading and reading a video.
|
| 497 |
+
|
| 498 |
+
```py
|
| 499 |
+
from huggingface_hub import hf_hub_download
|
| 500 |
+
from PIL import Image
|
| 501 |
+
import imageio
|
| 502 |
+
|
| 503 |
+
filename = "__assets__/pix2pix video/camel.mp4"
|
| 504 |
+
repo_id = "PAIR/Text2Video-Zero"
|
| 505 |
+
video_path = hf_hub_download(repo_type="space", repo_id=repo_id, filename=filename)
|
| 506 |
+
|
| 507 |
+
reader = imageio.get_reader(video_path, "ffmpeg")
|
| 508 |
+
frame_count = 8
|
| 509 |
+
video = [Image.fromarray(reader.get_data(i)) for i in range(frame_count)]
|
| 510 |
+
```
|
| 511 |
+
|
| 512 |
+
Load the [`StableDiffusionInstructPix2PixPipeline`] and set the [`~pipelines.text_to_video_synthesis.pipeline_text_to_video_zero.CrossFrameAttnProcessor`] for the UNet.
|
| 513 |
+
|
| 514 |
+
```py
|
| 515 |
+
import torch
|
| 516 |
+
from diffusers import StableDiffusionInstructPix2PixPipeline
|
| 517 |
+
from diffusers.pipelines.text_to_video_synthesis.pipeline_text_to_video_zero import CrossFrameAttnProcessor
|
| 518 |
+
|
| 519 |
+
pipeline = StableDiffusionInstructPix2PixPipeline.from_pretrained("timbrooks/instruct-pix2pix", torch_dtype=torch.float16).to("cuda")
|
| 520 |
+
pipeline.unet.set_attn_processor(CrossFrameAttnProcessor(batch_size=3))
|
| 521 |
+
```
|
| 522 |
+
|
| 523 |
+
Pass a prompt describing the change you want to apply to the video.
|
| 524 |
+
|
| 525 |
+
```py
|
| 526 |
+
prompt = "make it Van Gogh Starry Night style"
|
| 527 |
+
result = pipeline(prompt=[prompt] * len(video), image=video).images
|
| 528 |
+
imageio.mimsave("edited_video.mp4", result, fps=4)
|
| 529 |
+
```
|
| 530 |
+
|
| 531 |
+
</hfoption>
|
| 532 |
+
</hfoptions>
|
| 533 |
+
|
| 534 |
+
## Optimize
|
| 535 |
+
|
| 536 |
+
Video generation requires a lot of memory because you're generating many video frames at once. You can reduce your memory requirements at the expense of some inference speed. Try:
|
| 537 |
+
|
| 538 |
+
1. offloading pipeline components that are no longer needed to the CPU
|
| 539 |
+
2. feed-forward chunking runs the feed-forward layer in a loop instead of all at once
|
| 540 |
+
3. break up the number of frames the VAE has to decode into chunks instead of decoding them all at once
|
| 541 |
+
|
| 542 |
+
```diff
|
| 543 |
+
- pipeline.enable_model_cpu_offload()
|
| 544 |
+
- frames = pipeline(image, decode_chunk_size=8, generator=generator).frames[0]
|
| 545 |
+
+ pipeline.enable_model_cpu_offload()
|
| 546 |
+
+ pipeline.unet.enable_forward_chunking()
|
| 547 |
+
+ frames = pipeline(image, decode_chunk_size=2, generator=generator, num_frames=25).frames[0]
|
| 548 |
+
```
|
| 549 |
+
|
| 550 |
+
If memory is not an issue and you want to optimize for speed, try wrapping the UNet with [`torch.compile`](../optimization/torch2.0#torchcompile).
|
| 551 |
+
|
| 552 |
+
```diff
|
| 553 |
+
- pipeline.enable_model_cpu_offload()
|
| 554 |
+
+ pipeline.to("cuda")
|
| 555 |
+
+ pipeline.unet = torch.compile(pipeline.unet, mode="reduce-overhead", fullgraph=True)
|
| 556 |
+
```
|
| 557 |
+
|
| 558 |
+
## Quantization
|
| 559 |
+
|
| 560 |
+
Quantization helps reduce the memory requirements of very large models by storing model weights in a lower precision data type. However, quantization may have varying impact on video quality depending on the video model.
|
| 561 |
+
|
| 562 |
+
Refer to the [Quantization](../../quantization/overview) to learn more about supported quantization backends (bitsandbytes, torchao, gguf) and selecting a quantization backend that supports your use case.
|
tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/using-diffusers/textual_inversion_inference.md
ADDED
|
@@ -0,0 +1,65 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2024 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Textual Inversion
|
| 14 |
+
|
| 15 |
+
[Textual Inversion](https://huggingface.co/papers/2208.01618) is a method for generating personalized images of a concept. It works by fine-tuning a models word embeddings on 3-5 images of the concept (for example, pixel art) that is associated with a unique token (`<sks>`). This allows you to use the `<sks>` token in your prompt to trigger the model to generate pixel art images.
|
| 16 |
+
|
| 17 |
+
Textual Inversion weights are very lightweight and typically only a few KBs because they're only word embeddings. However, this also means the word embeddings need to be loaded after loading a model with [`~DiffusionPipeline.from_pretrained`].
|
| 18 |
+
|
| 19 |
+
```py
|
| 20 |
+
import torch
|
| 21 |
+
from diffusers import AutoPipelineForText2Image
|
| 22 |
+
|
| 23 |
+
pipeline = AutoPipelineForText2Image.from_pretrained(
|
| 24 |
+
"stable-diffusion-v1-5/stable-diffusion-v1-5",
|
| 25 |
+
torch_dtype=torch.float16
|
| 26 |
+
).to("cuda")
|
| 27 |
+
```
|
| 28 |
+
|
| 29 |
+
Load the word embeddings with [`~loaders.TextualInversionLoaderMixin.load_textual_inversion`] and include the unique token in the prompt to activate its generation.
|
| 30 |
+
|
| 31 |
+
```py
|
| 32 |
+
pipeline.load_textual_inversion("sd-concepts-library/gta5-artwork")
|
| 33 |
+
prompt = "A cute brown bear eating a slice of pizza, stunning color scheme, masterpiece, illustration, <gta5-artwork> style"
|
| 34 |
+
pipeline(prompt).images[0]
|
| 35 |
+
```
|
| 36 |
+
|
| 37 |
+
<div class="flex justify-center">
|
| 38 |
+
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/load_txt_embed.png" />
|
| 39 |
+
</div>
|
| 40 |
+
|
| 41 |
+
Textual Inversion can also be trained to learn *negative embeddings* to steer generation away from unwanted characteristics such as "blurry" or "ugly". It is useful for improving image quality.
|
| 42 |
+
|
| 43 |
+
EasyNegative is a widely used negative embedding that contains multiple learned negative concepts. Load the negative embeddings and specify the file name and token associated with the negative embeddings. Pass the token to `negative_prompt` in your pipeline to activate it.
|
| 44 |
+
|
| 45 |
+
```py
|
| 46 |
+
import torch
|
| 47 |
+
from diffusers import AutoPipelineForText2Image
|
| 48 |
+
|
| 49 |
+
pipeline = AutoPipelineForText2Image.from_pretrained(
|
| 50 |
+
"stable-diffusion-v1-5/stable-diffusion-v1-5",
|
| 51 |
+
torch_dtype=torch.float16
|
| 52 |
+
).to("cuda")
|
| 53 |
+
pipeline.load_textual_inversion(
|
| 54 |
+
"EvilEngine/easynegative",
|
| 55 |
+
weight_name="easynegative.safetensors",
|
| 56 |
+
token="easynegative"
|
| 57 |
+
)
|
| 58 |
+
prompt = "A cute brown bear eating a slice of pizza, stunning color scheme, masterpiece, illustration"
|
| 59 |
+
negative_prompt = "easynegative"
|
| 60 |
+
pipeline(prompt, negative_prompt).images[0]
|
| 61 |
+
```
|
| 62 |
+
|
| 63 |
+
<div class="flex justify-center">
|
| 64 |
+
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/load_neg_embed.png" />
|
| 65 |
+
</div>
|
tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/using-diffusers/unconditional_image_generation.md
ADDED
|
@@ -0,0 +1,55 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2024 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Unconditional image generation
|
| 14 |
+
|
| 15 |
+
[[open-in-colab]]
|
| 16 |
+
|
| 17 |
+
Unconditional image generation generates images that look like a random sample from the training data the model was trained on because the denoising process is not guided by any additional context like text or image.
|
| 18 |
+
|
| 19 |
+
To get started, use the [`DiffusionPipeline`] to load the [anton-l/ddpm-butterflies-128](https://huggingface.co/anton-l/ddpm-butterflies-128) checkpoint to generate images of butterflies. The [`DiffusionPipeline`] downloads and caches all the model components required to generate an image.
|
| 20 |
+
|
| 21 |
+
```py
|
| 22 |
+
from diffusers import DiffusionPipeline
|
| 23 |
+
|
| 24 |
+
generator = DiffusionPipeline.from_pretrained("anton-l/ddpm-butterflies-128").to("cuda")
|
| 25 |
+
image = generator().images[0]
|
| 26 |
+
image
|
| 27 |
+
```
|
| 28 |
+
|
| 29 |
+
<Tip>
|
| 30 |
+
|
| 31 |
+
Want to generate images of something else? Take a look at the training [guide](../training/unconditional_training) to learn how to train a model to generate your own images.
|
| 32 |
+
|
| 33 |
+
</Tip>
|
| 34 |
+
|
| 35 |
+
The output image is a [`PIL.Image`](https://pillow.readthedocs.io/en/stable/reference/Image.html?highlight=image#the-image-class) object that can be saved:
|
| 36 |
+
|
| 37 |
+
```py
|
| 38 |
+
image.save("generated_image.png")
|
| 39 |
+
```
|
| 40 |
+
|
| 41 |
+
You can also try experimenting with the `num_inference_steps` parameter, which controls the number of denoising steps. More denoising steps typically produce higher quality images, but it'll take longer to generate. Feel free to play around with this parameter to see how it affects the image quality.
|
| 42 |
+
|
| 43 |
+
```py
|
| 44 |
+
image = generator(num_inference_steps=100).images[0]
|
| 45 |
+
image
|
| 46 |
+
```
|
| 47 |
+
|
| 48 |
+
Try out the Space below to generate an image of a butterfly!
|
| 49 |
+
|
| 50 |
+
<iframe
|
| 51 |
+
src="https://stevhliu-unconditional-image-generation.hf.space"
|
| 52 |
+
frameborder="0"
|
| 53 |
+
width="850"
|
| 54 |
+
height="500"
|
| 55 |
+
></iframe>
|
tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/using-diffusers/weighted_prompts.md
ADDED
|
@@ -0,0 +1,435 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2024 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Prompt techniques
|
| 14 |
+
|
| 15 |
+
[[open-in-colab]]
|
| 16 |
+
|
| 17 |
+
Prompts are important because they describe what you want a diffusion model to generate. The best prompts are detailed, specific, and well-structured to help the model realize your vision. But crafting a great prompt takes time and effort and sometimes it may not be enough because language and words can be imprecise. This is where you need to boost your prompt with other techniques, such as prompt enhancing and prompt weighting, to get the results you want.
|
| 18 |
+
|
| 19 |
+
This guide will show you how you can use these prompt techniques to generate high-quality images with lower effort and adjust the weight of certain keywords in a prompt.
|
| 20 |
+
|
| 21 |
+
## Prompt engineering
|
| 22 |
+
|
| 23 |
+
> [!TIP]
|
| 24 |
+
> This is not an exhaustive guide on prompt engineering, but it will help you understand the necessary parts of a good prompt. We encourage you to continue experimenting with different prompts and combine them in new ways to see what works best. As you write more prompts, you'll develop an intuition for what works and what doesn't!
|
| 25 |
+
|
| 26 |
+
New diffusion models do a pretty good job of generating high-quality images from a basic prompt, but it is still important to create a well-written prompt to get the best results. Here are a few tips for writing a good prompt:
|
| 27 |
+
|
| 28 |
+
1. What is the image *medium*? Is it a photo, a painting, a 3D illustration, or something else?
|
| 29 |
+
2. What is the image *subject*? Is it a person, animal, object, or scene?
|
| 30 |
+
3. What *details* would you like to see in the image? This is where you can get really creative and have a lot of fun experimenting with different words to bring your image to life. For example, what is the lighting like? What is the vibe and aesthetic? What kind of art or illustration style are you looking for? The more specific and precise words you use, the better the model will understand what you want to generate.
|
| 31 |
+
|
| 32 |
+
<div class="flex gap-4">
|
| 33 |
+
<div>
|
| 34 |
+
<img class="rounded-xl" src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/plain-prompt.png"/>
|
| 35 |
+
<figcaption class="mt-2 text-center text-sm text-gray-500">"A photo of a banana-shaped couch in a living room"</figcaption>
|
| 36 |
+
</div>
|
| 37 |
+
<div>
|
| 38 |
+
<img class="rounded-xl" src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/detail-prompt.png"/>
|
| 39 |
+
<figcaption class="mt-2 text-center text-sm text-gray-500">"A vibrant yellow banana-shaped couch sits in a cozy living room, its curve cradling a pile of colorful cushions. on the wooden floor, a patterned rug adds a touch of eclectic charm, and a potted plant sits in the corner, reaching towards the sunlight filtering through the windows"</figcaption>
|
| 40 |
+
</div>
|
| 41 |
+
</div>
|
| 42 |
+
|
| 43 |
+
## Prompt enhancing with GPT2
|
| 44 |
+
|
| 45 |
+
Prompt enhancing is a technique for quickly improving prompt quality without spending too much effort constructing one. It uses a model like GPT2 pretrained on Stable Diffusion text prompts to automatically enrich a prompt with additional important keywords to generate high-quality images.
|
| 46 |
+
|
| 47 |
+
The technique works by curating a list of specific keywords and forcing the model to generate those words to enhance the original prompt. This way, your prompt can be "a cat" and GPT2 can enhance the prompt to "cinematic film still of a cat basking in the sun on a roof in Turkey, highly detailed, high budget hollywood movie, cinemascope, moody, epic, gorgeous, film grain quality sharp focus beautiful detailed intricate stunning amazing epic".
|
| 48 |
+
|
| 49 |
+
> [!TIP]
|
| 50 |
+
> You should also use a [*offset noise*](https://www.crosslabs.org//blog/diffusion-with-offset-noise) LoRA to improve the contrast in bright and dark images and create better lighting overall. This [LoRA](https://hf.co/stabilityai/stable-diffusion-xl-base-1.0/blob/main/sd_xl_offset_example-lora_1.0.safetensors) is available from [stabilityai/stable-diffusion-xl-base-1.0](https://hf.co/stabilityai/stable-diffusion-xl-base-1.0).
|
| 51 |
+
|
| 52 |
+
Start by defining certain styles and a list of words (you can check out a more comprehensive list of [words](https://hf.co/LykosAI/GPT-Prompt-Expansion-Fooocus-v2/blob/main/positive.txt) and [styles](https://github.com/lllyasviel/Fooocus/tree/main/sdxl_styles) used by Fooocus) to enhance a prompt with.
|
| 53 |
+
|
| 54 |
+
```py
|
| 55 |
+
import torch
|
| 56 |
+
from transformers import GenerationConfig, GPT2LMHeadModel, GPT2Tokenizer, LogitsProcessor, LogitsProcessorList
|
| 57 |
+
from diffusers import StableDiffusionXLPipeline
|
| 58 |
+
|
| 59 |
+
styles = {
|
| 60 |
+
"cinematic": "cinematic film still of {prompt}, highly detailed, high budget hollywood movie, cinemascope, moody, epic, gorgeous, film grain",
|
| 61 |
+
"anime": "anime artwork of {prompt}, anime style, key visual, vibrant, studio anime, highly detailed",
|
| 62 |
+
"photographic": "cinematic photo of {prompt}, 35mm photograph, film, professional, 4k, highly detailed",
|
| 63 |
+
"comic": "comic of {prompt}, graphic illustration, comic art, graphic novel art, vibrant, highly detailed",
|
| 64 |
+
"lineart": "line art drawing {prompt}, professional, sleek, modern, minimalist, graphic, line art, vector graphics",
|
| 65 |
+
"pixelart": " pixel-art {prompt}, low-res, blocky, pixel art style, 8-bit graphics",
|
| 66 |
+
}
|
| 67 |
+
|
| 68 |
+
words = [
|
| 69 |
+
"aesthetic", "astonishing", "beautiful", "breathtaking", "composition", "contrasted", "epic", "moody", "enhanced",
|
| 70 |
+
"exceptional", "fascinating", "flawless", "glamorous", "glorious", "illumination", "impressive", "improved",
|
| 71 |
+
"inspirational", "magnificent", "majestic", "hyperrealistic", "smooth", "sharp", "focus", "stunning", "detailed",
|
| 72 |
+
"intricate", "dramatic", "high", "quality", "perfect", "light", "ultra", "highly", "radiant", "satisfying",
|
| 73 |
+
"soothing", "sophisticated", "stylish", "sublime", "terrific", "touching", "timeless", "wonderful", "unbelievable",
|
| 74 |
+
"elegant", "awesome", "amazing", "dynamic", "trendy",
|
| 75 |
+
]
|
| 76 |
+
```
|
| 77 |
+
|
| 78 |
+
You may have noticed in the `words` list, there are certain words that can be paired together to create something more meaningful. For example, the words "high" and "quality" can be combined to create "high quality". Let's pair these words together and remove the words that can't be paired.
|
| 79 |
+
|
| 80 |
+
```py
|
| 81 |
+
word_pairs = ["highly detailed", "high quality", "enhanced quality", "perfect composition", "dynamic light"]
|
| 82 |
+
|
| 83 |
+
def find_and_order_pairs(s, pairs):
|
| 84 |
+
words = s.split()
|
| 85 |
+
found_pairs = []
|
| 86 |
+
for pair in pairs:
|
| 87 |
+
pair_words = pair.split()
|
| 88 |
+
if pair_words[0] in words and pair_words[1] in words:
|
| 89 |
+
found_pairs.append(pair)
|
| 90 |
+
words.remove(pair_words[0])
|
| 91 |
+
words.remove(pair_words[1])
|
| 92 |
+
|
| 93 |
+
for word in words[:]:
|
| 94 |
+
for pair in pairs:
|
| 95 |
+
if word in pair.split():
|
| 96 |
+
words.remove(word)
|
| 97 |
+
break
|
| 98 |
+
ordered_pairs = ", ".join(found_pairs)
|
| 99 |
+
remaining_s = ", ".join(words)
|
| 100 |
+
return ordered_pairs, remaining_s
|
| 101 |
+
```
|
| 102 |
+
|
| 103 |
+
Next, implement a custom [`~transformers.LogitsProcessor`] class that assigns tokens in the `words` list a value of 0 and assigns tokens not in the `words` list a negative value so they aren't picked during generation. This way, generation is biased towards words in the `words` list. After a word from the list is used, it is also assigned a negative value so it isn't picked again.
|
| 104 |
+
|
| 105 |
+
```py
|
| 106 |
+
class CustomLogitsProcessor(LogitsProcessor):
|
| 107 |
+
def __init__(self, bias):
|
| 108 |
+
super().__init__()
|
| 109 |
+
self.bias = bias
|
| 110 |
+
|
| 111 |
+
def __call__(self, input_ids, scores):
|
| 112 |
+
if len(input_ids.shape) == 2:
|
| 113 |
+
last_token_id = input_ids[0, -1]
|
| 114 |
+
self.bias[last_token_id] = -1e10
|
| 115 |
+
return scores + self.bias
|
| 116 |
+
|
| 117 |
+
word_ids = [tokenizer.encode(word, add_prefix_space=True)[0] for word in words]
|
| 118 |
+
bias = torch.full((tokenizer.vocab_size,), -float("Inf")).to("cuda")
|
| 119 |
+
bias[word_ids] = 0
|
| 120 |
+
processor = CustomLogitsProcessor(bias)
|
| 121 |
+
processor_list = LogitsProcessorList([processor])
|
| 122 |
+
```
|
| 123 |
+
|
| 124 |
+
Combine the prompt and the `cinematic` style prompt defined in the `styles` dictionary earlier.
|
| 125 |
+
|
| 126 |
+
```py
|
| 127 |
+
prompt = "a cat basking in the sun on a roof in Turkey"
|
| 128 |
+
style = "cinematic"
|
| 129 |
+
|
| 130 |
+
prompt = styles[style].format(prompt=prompt)
|
| 131 |
+
prompt
|
| 132 |
+
"cinematic film still of a cat basking in the sun on a roof in Turkey, highly detailed, high budget hollywood movie, cinemascope, moody, epic, gorgeous, film grain"
|
| 133 |
+
```
|
| 134 |
+
|
| 135 |
+
Load a GPT2 tokenizer and model from the [Gustavosta/MagicPrompt-Stable-Diffusion](https://huggingface.co/Gustavosta/MagicPrompt-Stable-Diffusion) checkpoint (this specific checkpoint is trained to generate prompts) to enhance the prompt.
|
| 136 |
+
|
| 137 |
+
```py
|
| 138 |
+
tokenizer = GPT2Tokenizer.from_pretrained("Gustavosta/MagicPrompt-Stable-Diffusion")
|
| 139 |
+
model = GPT2LMHeadModel.from_pretrained("Gustavosta/MagicPrompt-Stable-Diffusion", torch_dtype=torch.float16).to(
|
| 140 |
+
"cuda"
|
| 141 |
+
)
|
| 142 |
+
model.eval()
|
| 143 |
+
|
| 144 |
+
inputs = tokenizer(prompt, return_tensors="pt").to("cuda")
|
| 145 |
+
token_count = inputs["input_ids"].shape[1]
|
| 146 |
+
max_new_tokens = 50 - token_count
|
| 147 |
+
|
| 148 |
+
generation_config = GenerationConfig(
|
| 149 |
+
penalty_alpha=0.7,
|
| 150 |
+
top_k=50,
|
| 151 |
+
eos_token_id=model.config.eos_token_id,
|
| 152 |
+
pad_token_id=model.config.eos_token_id,
|
| 153 |
+
pad_token=model.config.pad_token_id,
|
| 154 |
+
do_sample=True,
|
| 155 |
+
)
|
| 156 |
+
|
| 157 |
+
with torch.no_grad():
|
| 158 |
+
generated_ids = model.generate(
|
| 159 |
+
input_ids=inputs["input_ids"],
|
| 160 |
+
attention_mask=inputs["attention_mask"],
|
| 161 |
+
max_new_tokens=max_new_tokens,
|
| 162 |
+
generation_config=generation_config,
|
| 163 |
+
logits_processor=proccesor_list,
|
| 164 |
+
)
|
| 165 |
+
```
|
| 166 |
+
|
| 167 |
+
Then you can combine the input prompt and the generated prompt. Feel free to take a look at what the generated prompt (`generated_part`) is, the word pairs that were found (`pairs`), and the remaining words (`words`). This is all packed together in the `enhanced_prompt`.
|
| 168 |
+
|
| 169 |
+
```py
|
| 170 |
+
output_tokens = [tokenizer.decode(generated_id, skip_special_tokens=True) for generated_id in generated_ids]
|
| 171 |
+
input_part, generated_part = output_tokens[0][: len(prompt)], output_tokens[0][len(prompt) :]
|
| 172 |
+
pairs, words = find_and_order_pairs(generated_part, word_pairs)
|
| 173 |
+
formatted_generated_part = pairs + ", " + words
|
| 174 |
+
enhanced_prompt = input_part + ", " + formatted_generated_part
|
| 175 |
+
enhanced_prompt
|
| 176 |
+
["cinematic film still of a cat basking in the sun on a roof in Turkey, highly detailed, high budget hollywood movie, cinemascope, moody, epic, gorgeous, film grain quality sharp focus beautiful detailed intricate stunning amazing epic"]
|
| 177 |
+
```
|
| 178 |
+
|
| 179 |
+
Finally, load a pipeline and the offset noise LoRA with a *low weight* to generate an image with the enhanced prompt.
|
| 180 |
+
|
| 181 |
+
```py
|
| 182 |
+
pipeline = StableDiffusionXLPipeline.from_pretrained(
|
| 183 |
+
"RunDiffusion/Juggernaut-XL-v9", torch_dtype=torch.float16, variant="fp16"
|
| 184 |
+
).to("cuda")
|
| 185 |
+
|
| 186 |
+
pipeline.load_lora_weights(
|
| 187 |
+
"stabilityai/stable-diffusion-xl-base-1.0",
|
| 188 |
+
weight_name="sd_xl_offset_example-lora_1.0.safetensors",
|
| 189 |
+
adapter_name="offset",
|
| 190 |
+
)
|
| 191 |
+
pipeline.set_adapters(["offset"], adapter_weights=[0.2])
|
| 192 |
+
|
| 193 |
+
image = pipeline(
|
| 194 |
+
enhanced_prompt,
|
| 195 |
+
width=1152,
|
| 196 |
+
height=896,
|
| 197 |
+
guidance_scale=7.5,
|
| 198 |
+
num_inference_steps=25,
|
| 199 |
+
).images[0]
|
| 200 |
+
image
|
| 201 |
+
```
|
| 202 |
+
|
| 203 |
+
<div class="flex gap-4">
|
| 204 |
+
<div>
|
| 205 |
+
<img class="rounded-xl" src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/non-enhanced-prompt.png"/>
|
| 206 |
+
<figcaption class="mt-2 text-center text-sm text-gray-500">"a cat basking in the sun on a roof in Turkey"</figcaption>
|
| 207 |
+
</div>
|
| 208 |
+
<div>
|
| 209 |
+
<img class="rounded-xl" src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/enhanced-prompt.png"/>
|
| 210 |
+
<figcaption class="mt-2 text-center text-sm text-gray-500">"cinematic film still of a cat basking in the sun on a roof in Turkey, highly detailed, high budget hollywood movie, cinemascope, moody, epic, gorgeous, film grain"</figcaption>
|
| 211 |
+
</div>
|
| 212 |
+
</div>
|
| 213 |
+
|
| 214 |
+
## Prompt weighting
|
| 215 |
+
|
| 216 |
+
Prompt weighting provides a way to emphasize or de-emphasize certain parts of a prompt, allowing for more control over the generated image. A prompt can include several concepts, which gets turned into contextualized text embeddings. The embeddings are used by the model to condition its cross-attention layers to generate an image (read the Stable Diffusion [blog post](https://huggingface.co/blog/stable_diffusion) to learn more about how it works).
|
| 217 |
+
|
| 218 |
+
Prompt weighting works by increasing or decreasing the scale of the text embedding vector that corresponds to its concept in the prompt because you may not necessarily want the model to focus on all concepts equally. The easiest way to prepare the prompt embeddings is to use [Stable Diffusion Long Prompt Weighted Embedding](https://github.com/xhinker/sd_embed) (sd_embed). Once you have the prompt-weighted embeddings, you can pass them to any pipeline that has a [prompt_embeds](https://huggingface.co/docs/diffusers/en/api/pipelines/stable_diffusion/text2img#diffusers.StableDiffusionPipeline.__call__.prompt_embeds) (and optionally [negative_prompt_embeds](https://huggingface.co/docs/diffusers/en/api/pipelines/stable_diffusion/text2img#diffusers.StableDiffusionPipeline.__call__.negative_prompt_embeds)) parameter, such as [`StableDiffusionPipeline`], [`StableDiffusionControlNetPipeline`], and [`StableDiffusionXLPipeline`].
|
| 219 |
+
|
| 220 |
+
<Tip>
|
| 221 |
+
|
| 222 |
+
If your favorite pipeline doesn't have a `prompt_embeds` parameter, please open an [issue](https://github.com/huggingface/diffusers/issues/new/choose) so we can add it!
|
| 223 |
+
|
| 224 |
+
</Tip>
|
| 225 |
+
|
| 226 |
+
This guide will show you how to weight your prompts with sd_embed.
|
| 227 |
+
|
| 228 |
+
Before you begin, make sure you have the latest version of sd_embed installed:
|
| 229 |
+
|
| 230 |
+
```bash
|
| 231 |
+
pip install git+https://github.com/xhinker/sd_embed.git@main
|
| 232 |
+
```
|
| 233 |
+
|
| 234 |
+
For this example, let's use [`StableDiffusionXLPipeline`].
|
| 235 |
+
|
| 236 |
+
```py
|
| 237 |
+
from diffusers import StableDiffusionXLPipeline, UniPCMultistepScheduler
|
| 238 |
+
import torch
|
| 239 |
+
|
| 240 |
+
pipe = StableDiffusionXLPipeline.from_pretrained("Lykon/dreamshaper-xl-1-0", torch_dtype=torch.float16)
|
| 241 |
+
pipe.scheduler = UniPCMultistepScheduler.from_config(pipe.scheduler.config)
|
| 242 |
+
pipe.to("cuda")
|
| 243 |
+
```
|
| 244 |
+
|
| 245 |
+
To upweight or downweight a concept, surround the text with parentheses. More parentheses applies a heavier weight on the text. You can also append a numerical multiplier to the text to indicate how much you want to increase or decrease its weights by.
|
| 246 |
+
|
| 247 |
+
| format | multiplier |
|
| 248 |
+
|---|---|
|
| 249 |
+
| `(hippo)` | increase by 1.1x |
|
| 250 |
+
| `((hippo))` | increase by 1.21x |
|
| 251 |
+
| `(hippo:1.5)` | increase by 1.5x |
|
| 252 |
+
| `(hippo:0.5)` | decrease by 4x |
|
| 253 |
+
|
| 254 |
+
Create a prompt and use a combination of parentheses and numerical multipliers to upweight various text.
|
| 255 |
+
|
| 256 |
+
```py
|
| 257 |
+
from sd_embed.embedding_funcs import get_weighted_text_embeddings_sdxl
|
| 258 |
+
|
| 259 |
+
prompt = """A whimsical and creative image depicting a hybrid creature that is a mix of a waffle and a hippopotamus.
|
| 260 |
+
This imaginative creature features the distinctive, bulky body of a hippo,
|
| 261 |
+
but with a texture and appearance resembling a golden-brown, crispy waffle.
|
| 262 |
+
The creature might have elements like waffle squares across its skin and a syrup-like sheen.
|
| 263 |
+
It's set in a surreal environment that playfully combines a natural water habitat of a hippo with elements of a breakfast table setting,
|
| 264 |
+
possibly including oversized utensils or plates in the background.
|
| 265 |
+
The image should evoke a sense of playful absurdity and culinary fantasy.
|
| 266 |
+
"""
|
| 267 |
+
|
| 268 |
+
neg_prompt = """\
|
| 269 |
+
skin spots,acnes,skin blemishes,age spot,(ugly:1.2),(duplicate:1.2),(morbid:1.21),(mutilated:1.2),\
|
| 270 |
+
(tranny:1.2),mutated hands,(poorly drawn hands:1.5),blurry,(bad anatomy:1.2),(bad proportions:1.3),\
|
| 271 |
+
extra limbs,(disfigured:1.2),(missing arms:1.2),(extra legs:1.2),(fused fingers:1.5),\
|
| 272 |
+
(too many fingers:1.5),(unclear eyes:1.2),lowers,bad hands,missing fingers,extra digit,\
|
| 273 |
+
bad hands,missing fingers,(extra arms and legs),(worst quality:2),(low quality:2),\
|
| 274 |
+
(normal quality:2),lowres,((monochrome)),((grayscale))
|
| 275 |
+
"""
|
| 276 |
+
```
|
| 277 |
+
|
| 278 |
+
Use the `get_weighted_text_embeddings_sdxl` function to generate the prompt embeddings and the negative prompt embeddings. It'll also generated the pooled and negative pooled prompt embeddings since you're using the SDXL model.
|
| 279 |
+
|
| 280 |
+
> [!TIP]
|
| 281 |
+
> You can safely ignore the error message below about the token index length exceeding the models maximum sequence length. All your tokens will be used in the embedding process.
|
| 282 |
+
>
|
| 283 |
+
> ```
|
| 284 |
+
> Token indices sequence length is longer than the specified maximum sequence length for this model
|
| 285 |
+
> ```
|
| 286 |
+
|
| 287 |
+
```py
|
| 288 |
+
(
|
| 289 |
+
prompt_embeds,
|
| 290 |
+
prompt_neg_embeds,
|
| 291 |
+
pooled_prompt_embeds,
|
| 292 |
+
negative_pooled_prompt_embeds
|
| 293 |
+
) = get_weighted_text_embeddings_sdxl(
|
| 294 |
+
pipe,
|
| 295 |
+
prompt=prompt,
|
| 296 |
+
neg_prompt=neg_prompt
|
| 297 |
+
)
|
| 298 |
+
|
| 299 |
+
image = pipe(
|
| 300 |
+
prompt_embeds=prompt_embeds,
|
| 301 |
+
negative_prompt_embeds=prompt_neg_embeds,
|
| 302 |
+
pooled_prompt_embeds=pooled_prompt_embeds,
|
| 303 |
+
negative_pooled_prompt_embeds=negative_pooled_prompt_embeds,
|
| 304 |
+
num_inference_steps=30,
|
| 305 |
+
height=1024,
|
| 306 |
+
width=1024 + 512,
|
| 307 |
+
guidance_scale=4.0,
|
| 308 |
+
generator=torch.Generator("cuda").manual_seed(2)
|
| 309 |
+
).images[0]
|
| 310 |
+
image
|
| 311 |
+
```
|
| 312 |
+
|
| 313 |
+
<div class="flex justify-center">
|
| 314 |
+
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/sd_embed_sdxl.png"/>
|
| 315 |
+
</div>
|
| 316 |
+
|
| 317 |
+
> [!TIP]
|
| 318 |
+
> Refer to the [sd_embed](https://github.com/xhinker/sd_embed) repository for additional details about long prompt weighting for FLUX.1, Stable Cascade, and Stable Diffusion 1.5.
|
| 319 |
+
|
| 320 |
+
### Textual inversion
|
| 321 |
+
|
| 322 |
+
[Textual inversion](../training/text_inversion) is a technique for learning a specific concept from some images which you can use to generate new images conditioned on that concept.
|
| 323 |
+
|
| 324 |
+
Create a pipeline and use the [`~loaders.TextualInversionLoaderMixin.load_textual_inversion`] function to load the textual inversion embeddings (feel free to browse the [Stable Diffusion Conceptualizer](https://huggingface.co/spaces/sd-concepts-library/stable-diffusion-conceptualizer) for 100+ trained concepts):
|
| 325 |
+
|
| 326 |
+
```py
|
| 327 |
+
import torch
|
| 328 |
+
from diffusers import StableDiffusionPipeline
|
| 329 |
+
|
| 330 |
+
pipe = StableDiffusionPipeline.from_pretrained(
|
| 331 |
+
"stable-diffusion-v1-5/stable-diffusion-v1-5",
|
| 332 |
+
torch_dtype=torch.float16,
|
| 333 |
+
).to("cuda")
|
| 334 |
+
pipe.load_textual_inversion("sd-concepts-library/midjourney-style")
|
| 335 |
+
```
|
| 336 |
+
|
| 337 |
+
Add the `<midjourney-style>` text to the prompt to trigger the textual inversion.
|
| 338 |
+
|
| 339 |
+
```py
|
| 340 |
+
from sd_embed.embedding_funcs import get_weighted_text_embeddings_sd15
|
| 341 |
+
|
| 342 |
+
prompt = """<midjourney-style> A whimsical and creative image depicting a hybrid creature that is a mix of a waffle and a hippopotamus.
|
| 343 |
+
This imaginative creature features the distinctive, bulky body of a hippo,
|
| 344 |
+
but with a texture and appearance resembling a golden-brown, crispy waffle.
|
| 345 |
+
The creature might have elements like waffle squares across its skin and a syrup-like sheen.
|
| 346 |
+
It's set in a surreal environment that playfully combines a natural water habitat of a hippo with elements of a breakfast table setting,
|
| 347 |
+
possibly including oversized utensils or plates in the background.
|
| 348 |
+
The image should evoke a sense of playful absurdity and culinary fantasy.
|
| 349 |
+
"""
|
| 350 |
+
|
| 351 |
+
neg_prompt = """\
|
| 352 |
+
skin spots,acnes,skin blemishes,age spot,(ugly:1.2),(duplicate:1.2),(morbid:1.21),(mutilated:1.2),\
|
| 353 |
+
(tranny:1.2),mutated hands,(poorly drawn hands:1.5),blurry,(bad anatomy:1.2),(bad proportions:1.3),\
|
| 354 |
+
extra limbs,(disfigured:1.2),(missing arms:1.2),(extra legs:1.2),(fused fingers:1.5),\
|
| 355 |
+
(too many fingers:1.5),(unclear eyes:1.2),lowers,bad hands,missing fingers,extra digit,\
|
| 356 |
+
bad hands,missing fingers,(extra arms and legs),(worst quality:2),(low quality:2),\
|
| 357 |
+
(normal quality:2),lowres,((monochrome)),((grayscale))
|
| 358 |
+
"""
|
| 359 |
+
```
|
| 360 |
+
|
| 361 |
+
Use the `get_weighted_text_embeddings_sd15` function to generate the prompt embeddings and the negative prompt embeddings.
|
| 362 |
+
|
| 363 |
+
```py
|
| 364 |
+
(
|
| 365 |
+
prompt_embeds,
|
| 366 |
+
prompt_neg_embeds,
|
| 367 |
+
) = get_weighted_text_embeddings_sd15(
|
| 368 |
+
pipe,
|
| 369 |
+
prompt=prompt,
|
| 370 |
+
neg_prompt=neg_prompt
|
| 371 |
+
)
|
| 372 |
+
|
| 373 |
+
image = pipe(
|
| 374 |
+
prompt_embeds=prompt_embeds,
|
| 375 |
+
negative_prompt_embeds=prompt_neg_embeds,
|
| 376 |
+
height=768,
|
| 377 |
+
width=896,
|
| 378 |
+
guidance_scale=4.0,
|
| 379 |
+
generator=torch.Generator("cuda").manual_seed(2)
|
| 380 |
+
).images[0]
|
| 381 |
+
image
|
| 382 |
+
```
|
| 383 |
+
|
| 384 |
+
<div class="flex justify-center">
|
| 385 |
+
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/sd_embed_textual_inversion.png"/>
|
| 386 |
+
</div>
|
| 387 |
+
|
| 388 |
+
### DreamBooth
|
| 389 |
+
|
| 390 |
+
[DreamBooth](../training/dreambooth) is a technique for generating contextualized images of a subject given just a few images of the subject to train on. It is similar to textual inversion, but DreamBooth trains the full model whereas textual inversion only fine-tunes the text embeddings. This means you should use [`~DiffusionPipeline.from_pretrained`] to load the DreamBooth model (feel free to browse the [Stable Diffusion Dreambooth Concepts Library](https://huggingface.co/sd-dreambooth-library) for 100+ trained models):
|
| 391 |
+
|
| 392 |
+
```py
|
| 393 |
+
import torch
|
| 394 |
+
from diffusers import DiffusionPipeline, UniPCMultistepScheduler
|
| 395 |
+
|
| 396 |
+
pipe = DiffusionPipeline.from_pretrained("sd-dreambooth-library/dndcoverart-v1", torch_dtype=torch.float16).to("cuda")
|
| 397 |
+
pipe.scheduler = UniPCMultistepScheduler.from_config(pipe.scheduler.config)
|
| 398 |
+
```
|
| 399 |
+
|
| 400 |
+
Depending on the model you use, you'll need to incorporate the model's unique identifier into your prompt. For example, the `dndcoverart-v1` model uses the identifier `dndcoverart`:
|
| 401 |
+
|
| 402 |
+
```py
|
| 403 |
+
from sd_embed.embedding_funcs import get_weighted_text_embeddings_sd15
|
| 404 |
+
|
| 405 |
+
prompt = """dndcoverart of A whimsical and creative image depicting a hybrid creature that is a mix of a waffle and a hippopotamus.
|
| 406 |
+
This imaginative creature features the distinctive, bulky body of a hippo,
|
| 407 |
+
but with a texture and appearance resembling a golden-brown, crispy waffle.
|
| 408 |
+
The creature might have elements like waffle squares across its skin and a syrup-like sheen.
|
| 409 |
+
It's set in a surreal environment that playfully combines a natural water habitat of a hippo with elements of a breakfast table setting,
|
| 410 |
+
possibly including oversized utensils or plates in the background.
|
| 411 |
+
The image should evoke a sense of playful absurdity and culinary fantasy.
|
| 412 |
+
"""
|
| 413 |
+
|
| 414 |
+
neg_prompt = """\
|
| 415 |
+
skin spots,acnes,skin blemishes,age spot,(ugly:1.2),(duplicate:1.2),(morbid:1.21),(mutilated:1.2),\
|
| 416 |
+
(tranny:1.2),mutated hands,(poorly drawn hands:1.5),blurry,(bad anatomy:1.2),(bad proportions:1.3),\
|
| 417 |
+
extra limbs,(disfigured:1.2),(missing arms:1.2),(extra legs:1.2),(fused fingers:1.5),\
|
| 418 |
+
(too many fingers:1.5),(unclear eyes:1.2),lowers,bad hands,missing fingers,extra digit,\
|
| 419 |
+
bad hands,missing fingers,(extra arms and legs),(worst quality:2),(low quality:2),\
|
| 420 |
+
(normal quality:2),lowres,((monochrome)),((grayscale))
|
| 421 |
+
"""
|
| 422 |
+
|
| 423 |
+
(
|
| 424 |
+
prompt_embeds
|
| 425 |
+
, prompt_neg_embeds
|
| 426 |
+
) = get_weighted_text_embeddings_sd15(
|
| 427 |
+
pipe
|
| 428 |
+
, prompt = prompt
|
| 429 |
+
, neg_prompt = neg_prompt
|
| 430 |
+
)
|
| 431 |
+
```
|
| 432 |
+
|
| 433 |
+
<div class="flex justify-center">
|
| 434 |
+
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/sd_embed_dreambooth.png"/>
|
| 435 |
+
</div>
|
tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/using-diffusers/write_own_pipeline.md
ADDED
|
@@ -0,0 +1,293 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2024 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Understanding pipelines, models and schedulers
|
| 14 |
+
|
| 15 |
+
[[open-in-colab]]
|
| 16 |
+
|
| 17 |
+
🧨 Diffusers is designed to be a user-friendly and flexible toolbox for building diffusion systems tailored to your use-case. At the core of the toolbox are models and schedulers. While the [`DiffusionPipeline`] bundles these components together for convenience, you can also unbundle the pipeline and use the models and schedulers separately to create new diffusion systems.
|
| 18 |
+
|
| 19 |
+
In this tutorial, you'll learn how to use models and schedulers to assemble a diffusion system for inference, starting with a basic pipeline and then progressing to the Stable Diffusion pipeline.
|
| 20 |
+
|
| 21 |
+
## Deconstruct a basic pipeline
|
| 22 |
+
|
| 23 |
+
A pipeline is a quick and easy way to run a model for inference, requiring no more than four lines of code to generate an image:
|
| 24 |
+
|
| 25 |
+
```py
|
| 26 |
+
>>> from diffusers import DDPMPipeline
|
| 27 |
+
|
| 28 |
+
>>> ddpm = DDPMPipeline.from_pretrained("google/ddpm-cat-256", use_safetensors=True).to("cuda")
|
| 29 |
+
>>> image = ddpm(num_inference_steps=25).images[0]
|
| 30 |
+
>>> image
|
| 31 |
+
```
|
| 32 |
+
|
| 33 |
+
<div class="flex justify-center">
|
| 34 |
+
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/ddpm-cat.png" alt="Image of cat created from DDPMPipeline"/>
|
| 35 |
+
</div>
|
| 36 |
+
|
| 37 |
+
That was super easy, but how did the pipeline do that? Let's breakdown the pipeline and take a look at what's happening under the hood.
|
| 38 |
+
|
| 39 |
+
In the example above, the pipeline contains a [`UNet2DModel`] model and a [`DDPMScheduler`]. The pipeline denoises an image by taking random noise the size of the desired output and passing it through the model several times. At each timestep, the model predicts the *noise residual* and the scheduler uses it to predict a less noisy image. The pipeline repeats this process until it reaches the end of the specified number of inference steps.
|
| 40 |
+
|
| 41 |
+
To recreate the pipeline with the model and scheduler separately, let's write our own denoising process.
|
| 42 |
+
|
| 43 |
+
1. Load the model and scheduler:
|
| 44 |
+
|
| 45 |
+
```py
|
| 46 |
+
>>> from diffusers import DDPMScheduler, UNet2DModel
|
| 47 |
+
|
| 48 |
+
>>> scheduler = DDPMScheduler.from_pretrained("google/ddpm-cat-256")
|
| 49 |
+
>>> model = UNet2DModel.from_pretrained("google/ddpm-cat-256", use_safetensors=True).to("cuda")
|
| 50 |
+
```
|
| 51 |
+
|
| 52 |
+
2. Set the number of timesteps to run the denoising process for:
|
| 53 |
+
|
| 54 |
+
```py
|
| 55 |
+
>>> scheduler.set_timesteps(50)
|
| 56 |
+
```
|
| 57 |
+
|
| 58 |
+
3. Setting the scheduler timesteps creates a tensor with evenly spaced elements in it, 50 in this example. Each element corresponds to a timestep at which the model denoises an image. When you create the denoising loop later, you'll iterate over this tensor to denoise an image:
|
| 59 |
+
|
| 60 |
+
```py
|
| 61 |
+
>>> scheduler.timesteps
|
| 62 |
+
tensor([980, 960, 940, 920, 900, 880, 860, 840, 820, 800, 780, 760, 740, 720,
|
| 63 |
+
700, 680, 660, 640, 620, 600, 580, 560, 540, 520, 500, 480, 460, 440,
|
| 64 |
+
420, 400, 380, 360, 340, 320, 300, 280, 260, 240, 220, 200, 180, 160,
|
| 65 |
+
140, 120, 100, 80, 60, 40, 20, 0])
|
| 66 |
+
```
|
| 67 |
+
|
| 68 |
+
4. Create some random noise with the same shape as the desired output:
|
| 69 |
+
|
| 70 |
+
```py
|
| 71 |
+
>>> import torch
|
| 72 |
+
|
| 73 |
+
>>> sample_size = model.config.sample_size
|
| 74 |
+
>>> noise = torch.randn((1, 3, sample_size, sample_size), device="cuda")
|
| 75 |
+
```
|
| 76 |
+
|
| 77 |
+
5. Now write a loop to iterate over the timesteps. At each timestep, the model does a [`UNet2DModel.forward`] pass and returns the noisy residual. The scheduler's [`~DDPMScheduler.step`] method takes the noisy residual, timestep, and input and it predicts the image at the previous timestep. This output becomes the next input to the model in the denoising loop, and it'll repeat until it reaches the end of the `timesteps` array.
|
| 78 |
+
|
| 79 |
+
```py
|
| 80 |
+
>>> input = noise
|
| 81 |
+
|
| 82 |
+
>>> for t in scheduler.timesteps:
|
| 83 |
+
... with torch.no_grad():
|
| 84 |
+
... noisy_residual = model(input, t).sample
|
| 85 |
+
... previous_noisy_sample = scheduler.step(noisy_residual, t, input).prev_sample
|
| 86 |
+
... input = previous_noisy_sample
|
| 87 |
+
```
|
| 88 |
+
|
| 89 |
+
This is the entire denoising process, and you can use this same pattern to write any diffusion system.
|
| 90 |
+
|
| 91 |
+
6. The last step is to convert the denoised output into an image:
|
| 92 |
+
|
| 93 |
+
```py
|
| 94 |
+
>>> from PIL import Image
|
| 95 |
+
>>> import numpy as np
|
| 96 |
+
|
| 97 |
+
>>> image = (input / 2 + 0.5).clamp(0, 1).squeeze()
|
| 98 |
+
>>> image = (image.permute(1, 2, 0) * 255).round().to(torch.uint8).cpu().numpy()
|
| 99 |
+
>>> image = Image.fromarray(image)
|
| 100 |
+
>>> image
|
| 101 |
+
```
|
| 102 |
+
|
| 103 |
+
In the next section, you'll put your skills to the test and breakdown the more complex Stable Diffusion pipeline. The steps are more or less the same. You'll initialize the necessary components, and set the number of timesteps to create a `timestep` array. The `timestep` array is used in the denoising loop, and for each element in this array, the model predicts a less noisy image. The denoising loop iterates over the `timestep`'s, and at each timestep, it outputs a noisy residual and the scheduler uses it to predict a less noisy image at the previous timestep. This process is repeated until you reach the end of the `timestep` array.
|
| 104 |
+
|
| 105 |
+
Let's try it out!
|
| 106 |
+
|
| 107 |
+
## Deconstruct the Stable Diffusion pipeline
|
| 108 |
+
|
| 109 |
+
Stable Diffusion is a text-to-image *latent diffusion* model. It is called a latent diffusion model because it works with a lower-dimensional representation of the image instead of the actual pixel space, which makes it more memory efficient. The encoder compresses the image into a smaller representation, and a decoder converts the compressed representation back into an image. For text-to-image models, you'll need a tokenizer and an encoder to generate text embeddings. From the previous example, you already know you need a UNet model and a scheduler.
|
| 110 |
+
|
| 111 |
+
As you can see, this is already more complex than the DDPM pipeline which only contains a UNet model. The Stable Diffusion model has three separate pretrained models.
|
| 112 |
+
|
| 113 |
+
<Tip>
|
| 114 |
+
|
| 115 |
+
💡 Read the [How does Stable Diffusion work?](https://huggingface.co/blog/stable_diffusion#how-does-stable-diffusion-work) blog for more details about how the VAE, UNet, and text encoder models work.
|
| 116 |
+
|
| 117 |
+
</Tip>
|
| 118 |
+
|
| 119 |
+
Now that you know what you need for the Stable Diffusion pipeline, load all these components with the [`~ModelMixin.from_pretrained`] method. You can find them in the pretrained [`stable-diffusion-v1-5/stable-diffusion-v1-5`](https://huggingface.co/stable-diffusion-v1-5/stable-diffusion-v1-5) checkpoint, and each component is stored in a separate subfolder:
|
| 120 |
+
|
| 121 |
+
```py
|
| 122 |
+
>>> from PIL import Image
|
| 123 |
+
>>> import torch
|
| 124 |
+
>>> from transformers import CLIPTextModel, CLIPTokenizer
|
| 125 |
+
>>> from diffusers import AutoencoderKL, UNet2DConditionModel, PNDMScheduler
|
| 126 |
+
|
| 127 |
+
>>> vae = AutoencoderKL.from_pretrained("CompVis/stable-diffusion-v1-4", subfolder="vae", use_safetensors=True)
|
| 128 |
+
>>> tokenizer = CLIPTokenizer.from_pretrained("CompVis/stable-diffusion-v1-4", subfolder="tokenizer")
|
| 129 |
+
>>> text_encoder = CLIPTextModel.from_pretrained(
|
| 130 |
+
... "CompVis/stable-diffusion-v1-4", subfolder="text_encoder", use_safetensors=True
|
| 131 |
+
... )
|
| 132 |
+
>>> unet = UNet2DConditionModel.from_pretrained(
|
| 133 |
+
... "CompVis/stable-diffusion-v1-4", subfolder="unet", use_safetensors=True
|
| 134 |
+
... )
|
| 135 |
+
```
|
| 136 |
+
|
| 137 |
+
Instead of the default [`PNDMScheduler`], exchange it for the [`UniPCMultistepScheduler`] to see how easy it is to plug a different scheduler in:
|
| 138 |
+
|
| 139 |
+
```py
|
| 140 |
+
>>> from diffusers import UniPCMultistepScheduler
|
| 141 |
+
|
| 142 |
+
>>> scheduler = UniPCMultistepScheduler.from_pretrained("CompVis/stable-diffusion-v1-4", subfolder="scheduler")
|
| 143 |
+
```
|
| 144 |
+
|
| 145 |
+
To speed up inference, move the models to a GPU since, unlike the scheduler, they have trainable weights:
|
| 146 |
+
|
| 147 |
+
```py
|
| 148 |
+
>>> torch_device = "cuda"
|
| 149 |
+
>>> vae.to(torch_device)
|
| 150 |
+
>>> text_encoder.to(torch_device)
|
| 151 |
+
>>> unet.to(torch_device)
|
| 152 |
+
```
|
| 153 |
+
|
| 154 |
+
### Create text embeddings
|
| 155 |
+
|
| 156 |
+
The next step is to tokenize the text to generate embeddings. The text is used to condition the UNet model and steer the diffusion process towards something that resembles the input prompt.
|
| 157 |
+
|
| 158 |
+
<Tip>
|
| 159 |
+
|
| 160 |
+
💡 The `guidance_scale` parameter determines how much weight should be given to the prompt when generating an image.
|
| 161 |
+
|
| 162 |
+
</Tip>
|
| 163 |
+
|
| 164 |
+
Feel free to choose any prompt you like if you want to generate something else!
|
| 165 |
+
|
| 166 |
+
```py
|
| 167 |
+
>>> prompt = ["a photograph of an astronaut riding a horse"]
|
| 168 |
+
>>> height = 512 # default height of Stable Diffusion
|
| 169 |
+
>>> width = 512 # default width of Stable Diffusion
|
| 170 |
+
>>> num_inference_steps = 25 # Number of denoising steps
|
| 171 |
+
>>> guidance_scale = 7.5 # Scale for classifier-free guidance
|
| 172 |
+
>>> generator = torch.manual_seed(0) # Seed generator to create the initial latent noise
|
| 173 |
+
>>> batch_size = len(prompt)
|
| 174 |
+
```
|
| 175 |
+
|
| 176 |
+
Tokenize the text and generate the embeddings from the prompt:
|
| 177 |
+
|
| 178 |
+
```py
|
| 179 |
+
>>> text_input = tokenizer(
|
| 180 |
+
... prompt, padding="max_length", max_length=tokenizer.model_max_length, truncation=True, return_tensors="pt"
|
| 181 |
+
... )
|
| 182 |
+
|
| 183 |
+
>>> with torch.no_grad():
|
| 184 |
+
... text_embeddings = text_encoder(text_input.input_ids.to(torch_device))[0]
|
| 185 |
+
```
|
| 186 |
+
|
| 187 |
+
You'll also need to generate the *unconditional text embeddings* which are the embeddings for the padding token. These need to have the same shape (`batch_size` and `seq_length`) as the conditional `text_embeddings`:
|
| 188 |
+
|
| 189 |
+
```py
|
| 190 |
+
>>> max_length = text_input.input_ids.shape[-1]
|
| 191 |
+
>>> uncond_input = tokenizer([""] * batch_size, padding="max_length", max_length=max_length, return_tensors="pt")
|
| 192 |
+
>>> uncond_embeddings = text_encoder(uncond_input.input_ids.to(torch_device))[0]
|
| 193 |
+
```
|
| 194 |
+
|
| 195 |
+
Let's concatenate the conditional and unconditional embeddings into a batch to avoid doing two forward passes:
|
| 196 |
+
|
| 197 |
+
```py
|
| 198 |
+
>>> text_embeddings = torch.cat([uncond_embeddings, text_embeddings])
|
| 199 |
+
```
|
| 200 |
+
|
| 201 |
+
### Create random noise
|
| 202 |
+
|
| 203 |
+
Next, generate some initial random noise as a starting point for the diffusion process. This is the latent representation of the image, and it'll be gradually denoised. At this point, the `latent` image is smaller than the final image size but that's okay though because the model will transform it into the final 512x512 image dimensions later.
|
| 204 |
+
|
| 205 |
+
<Tip>
|
| 206 |
+
|
| 207 |
+
💡 The height and width are divided by 8 because the `vae` model has 3 down-sampling layers. You can check by running the following:
|
| 208 |
+
|
| 209 |
+
```py
|
| 210 |
+
2 ** (len(vae.config.block_out_channels) - 1) == 8
|
| 211 |
+
```
|
| 212 |
+
|
| 213 |
+
</Tip>
|
| 214 |
+
|
| 215 |
+
```py
|
| 216 |
+
>>> latents = torch.randn(
|
| 217 |
+
... (batch_size, unet.config.in_channels, height // 8, width // 8),
|
| 218 |
+
... generator=generator,
|
| 219 |
+
... device=torch_device,
|
| 220 |
+
... )
|
| 221 |
+
```
|
| 222 |
+
|
| 223 |
+
### Denoise the image
|
| 224 |
+
|
| 225 |
+
Start by scaling the input with the initial noise distribution, *sigma*, the noise scale value, which is required for improved schedulers like [`UniPCMultistepScheduler`]:
|
| 226 |
+
|
| 227 |
+
```py
|
| 228 |
+
>>> latents = latents * scheduler.init_noise_sigma
|
| 229 |
+
```
|
| 230 |
+
|
| 231 |
+
The last step is to create the denoising loop that'll progressively transform the pure noise in `latents` to an image described by your prompt. Remember, the denoising loop needs to do three things:
|
| 232 |
+
|
| 233 |
+
1. Set the scheduler's timesteps to use during denoising.
|
| 234 |
+
2. Iterate over the timesteps.
|
| 235 |
+
3. At each timestep, call the UNet model to predict the noise residual and pass it to the scheduler to compute the previous noisy sample.
|
| 236 |
+
|
| 237 |
+
```py
|
| 238 |
+
>>> from tqdm.auto import tqdm
|
| 239 |
+
|
| 240 |
+
>>> scheduler.set_timesteps(num_inference_steps)
|
| 241 |
+
|
| 242 |
+
>>> for t in tqdm(scheduler.timesteps):
|
| 243 |
+
... # expand the latents if we are doing classifier-free guidance to avoid doing two forward passes.
|
| 244 |
+
... latent_model_input = torch.cat([latents] * 2)
|
| 245 |
+
|
| 246 |
+
... latent_model_input = scheduler.scale_model_input(latent_model_input, timestep=t)
|
| 247 |
+
|
| 248 |
+
... # predict the noise residual
|
| 249 |
+
... with torch.no_grad():
|
| 250 |
+
... noise_pred = unet(latent_model_input, t, encoder_hidden_states=text_embeddings).sample
|
| 251 |
+
|
| 252 |
+
... # perform guidance
|
| 253 |
+
... noise_pred_uncond, noise_pred_text = noise_pred.chunk(2)
|
| 254 |
+
... noise_pred = noise_pred_uncond + guidance_scale * (noise_pred_text - noise_pred_uncond)
|
| 255 |
+
|
| 256 |
+
... # compute the previous noisy sample x_t -> x_t-1
|
| 257 |
+
... latents = scheduler.step(noise_pred, t, latents).prev_sample
|
| 258 |
+
```
|
| 259 |
+
|
| 260 |
+
### Decode the image
|
| 261 |
+
|
| 262 |
+
The final step is to use the `vae` to decode the latent representation into an image and get the decoded output with `sample`:
|
| 263 |
+
|
| 264 |
+
```py
|
| 265 |
+
# scale and decode the image latents with vae
|
| 266 |
+
latents = 1 / 0.18215 * latents
|
| 267 |
+
with torch.no_grad():
|
| 268 |
+
image = vae.decode(latents).sample
|
| 269 |
+
```
|
| 270 |
+
|
| 271 |
+
Lastly, convert the image to a `PIL.Image` to see your generated image!
|
| 272 |
+
|
| 273 |
+
```py
|
| 274 |
+
>>> image = (image / 2 + 0.5).clamp(0, 1).squeeze()
|
| 275 |
+
>>> image = (image.permute(1, 2, 0) * 255).to(torch.uint8).cpu().numpy()
|
| 276 |
+
>>> image = Image.fromarray(image)
|
| 277 |
+
>>> image
|
| 278 |
+
```
|
| 279 |
+
|
| 280 |
+
<div class="flex justify-center">
|
| 281 |
+
<img src="https://huggingface.co/blog/assets/98_stable_diffusion/stable_diffusion_k_lms.png"/>
|
| 282 |
+
</div>
|
| 283 |
+
|
| 284 |
+
## Next steps
|
| 285 |
+
|
| 286 |
+
From basic to complex pipelines, you've seen that all you really need to write your own diffusion system is a denoising loop. The loop should set the scheduler's timesteps, iterate over them, and alternate between calling the UNet model to predict the noise residual and passing it to the scheduler to compute the previous noisy sample.
|
| 287 |
+
|
| 288 |
+
This is really what 🧨 Diffusers is designed for: to make it intuitive and easy to write your own diffusion system using models and schedulers.
|
| 289 |
+
|
| 290 |
+
For your next steps, feel free to:
|
| 291 |
+
|
| 292 |
+
* Learn how to [build and contribute a pipeline](../using-diffusers/contribute_pipeline) to 🧨 Diffusers. We can't wait and see what you'll come up with!
|
| 293 |
+
* Explore [existing pipelines](../api/pipelines/overview) in the library, and see if you can deconstruct and build a pipeline from scratch using the models and schedulers separately.
|
tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ja/_toctree.yml
ADDED
|
@@ -0,0 +1,16 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
- sections:
|
| 2 |
+
- local: index
|
| 3 |
+
title: 🧨 Diffusers
|
| 4 |
+
- local: quicktour
|
| 5 |
+
title: クイックツアー
|
| 6 |
+
- local: stable_diffusion
|
| 7 |
+
title: 有効で効率の良い拡散モデル
|
| 8 |
+
- local: installation
|
| 9 |
+
title: インストール
|
| 10 |
+
title: はじめに
|
| 11 |
+
- sections:
|
| 12 |
+
- local: tutorials/tutorial_overview
|
| 13 |
+
title: 概要
|
| 14 |
+
- local: tutorials/autopipeline
|
| 15 |
+
title: AutoPipeline
|
| 16 |
+
title: チュートリアル
|
tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ja/index.md
ADDED
|
@@ -0,0 +1,48 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2024 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
<p align="center">
|
| 14 |
+
<br>
|
| 15 |
+
<img src="https://raw.githubusercontent.com/huggingface/diffusers/77aadfee6a891ab9fcfb780f87c693f7a5beeb8e/docs/source/imgs/diffusers_library.jpg" width="400"/>
|
| 16 |
+
<br>
|
| 17 |
+
</p>
|
| 18 |
+
|
| 19 |
+
# Diffusers
|
| 20 |
+
|
| 21 |
+
🤗 Diffusers は、画像や音声、さらには分子の3D構造を生成するための、最先端の事前学習済みDiffusion Model(拡散モデル)を提供するライブラリです。シンプルな生成ソリューションをお探しの場合でも、独自の拡散モデルをトレーニングしたい場合でも、🤗 Diffusers はその両方をサポートするモジュール式のツールボックスです。私たちのライブラリは、[性能より使いやすさ](conceptual/philosophy#usability-over-performance)、[簡単よりシンプル](conceptual/philosophy#simple-over-easy)、[抽象化よりカスタマイズ性](conceptual/philosophy#tweakable-contributorfriendly-over-abstraction)に重点を置いて設計されています。
|
| 22 |
+
|
| 23 |
+
このライブラリには3つの主要コンポーネントがあります:
|
| 24 |
+
|
| 25 |
+
- 数行のコードで推論可能な最先端の[拡散パイプライン](api/pipelines/overview)。Diffusersには多くのパイプラインがあります。利用可能なパイプラインを網羅したリストと、それらが解決するタスクについては、パイプラインの[概要](https://huggingface.co/docs/diffusers/api/pipelines/overview)の表をご覧ください。
|
| 26 |
+
- 生成速度と品質のトレードオフのバランスを取る交換可能な[ノイズスケジューラ](api/schedulers/overview)
|
| 27 |
+
- ビルディングブロックとして使用することができ、スケジューラと組み合わせることで、エンドツーエンドの拡散モデルを構築可能な事前学習済み[モデル](api/models)
|
| 28 |
+
|
| 29 |
+
<div class="mt-10">
|
| 30 |
+
<div class="w-full flex flex-col space-y-4 md:space-y-0 md:grid md:grid-cols-2 md:gap-y-4 md:gap-x-5">
|
| 31 |
+
<a class="!no-underline border dark:border-gray-700 p-5 rounded-lg shadow hover:shadow-lg" href="./tutorials/tutorial_overview"
|
| 32 |
+
><div class="w-full text-center bg-gradient-to-br from-blue-400 to-blue-500 rounded-lg py-1.5 font-semibold mb-5 text-white text-lg leading-relaxed">チュートリアル</div>
|
| 33 |
+
<p class="text-gray-700">出力の生成、独自の拡散システムの構築、拡散モデルのトレーニングを開始するために必要な基本的なスキルを学ぶことができます。初めて 🤗Diffusersを使用する場合は、ここから始めることをおすすめします!</p>
|
| 34 |
+
</a>
|
| 35 |
+
<a class="!no-underline border dark:border-gray-700 p-5 rounded-lg shadow hover:shadow-lg" href="./using-diffusers/loading_overview"
|
| 36 |
+
><div class="w-full text-center bg-gradient-to-br from-indigo-400 to-indigo-500 rounded-lg py-1.5 font-semibold mb-5 text-white text-lg leading-relaxed">ガイド</div>
|
| 37 |
+
<p class="text-gray-700">パイプライン、モデル、スケジューラの読み込みに役立つ実践的なガイドです。また、特定のタスクにパイプラインを使用する方法、出力の生成方法を制御する方法、生成速度を最適化する方法、さまざまなトレーニング手法についても学ぶことができます。</p>
|
| 38 |
+
</a>
|
| 39 |
+
<a class="!no-underline border dark:border-gray-700 p-5 rounded-lg shadow hover:shadow-lg" href="./conceptual/philosophy"
|
| 40 |
+
><div class="w-full text-center bg-gradient-to-br from-pink-400 to-pink-500 rounded-lg py-1.5 font-semibold mb-5 text-white text-lg leading-relaxed">Conceptual guides</div>
|
| 41 |
+
<p class="text-gray-700">ライブラリがなぜこのように設計されたのかを理解し、ライブラリを利用する際の倫理的ガイドラインや安全対策について詳しく学べます。</p>
|
| 42 |
+
</a>
|
| 43 |
+
<a class="!no-underline border dark:border-gray-700 p-5 rounded-lg shadow hover:shadow-lg" href="./api/models/overview"
|
| 44 |
+
><div class="w-full text-center bg-gradient-to-br from-purple-400 to-purple-500 rounded-lg py-1.5 font-semibold mb-5 text-white text-lg leading-relaxed">リファレンス</div>
|
| 45 |
+
<p class="text-gray-700">🤗 Diffusersのクラスとメソッドがどのように機能するかについての技術的な説明です。</p>
|
| 46 |
+
</a>
|
| 47 |
+
</div>
|
| 48 |
+
</div>
|
tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ja/installation.md
ADDED
|
@@ -0,0 +1,145 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2024 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# インストール
|
| 14 |
+
|
| 15 |
+
お使いのディープラーニングライブラリに合わせてDiffusersをインストールできます。
|
| 16 |
+
|
| 17 |
+
🤗 DiffusersはPython 3.8+、PyTorch 1.7.0+、Flaxでテストされています。使用するディープラーニングライブラリの以下のインストール手順に従ってください:
|
| 18 |
+
|
| 19 |
+
- [PyTorch](https://pytorch.org/get-started/locally/)のインストール手順。
|
| 20 |
+
- [Flax](https://flax.readthedocs.io/en/latest/)のインストール手順。
|
| 21 |
+
|
| 22 |
+
## pip でインストール
|
| 23 |
+
|
| 24 |
+
Diffusersは[仮想環境](https://docs.python.org/3/library/venv.html)の中でインストールすることが推奨されています。
|
| 25 |
+
Python の仮想環境についてよく知らない場合は、こちらの [ガイド](https://packaging.python.org/guides/installing-using-pip-and-virtual-environments/) を参照してください。
|
| 26 |
+
仮想環境は異なるプロジェクトの管理を容易にし、依存関係間の互換性の問題を回避します。
|
| 27 |
+
|
| 28 |
+
ではさっそく、プロジェクトディレクトリに仮想環境を作ってみます:
|
| 29 |
+
|
| 30 |
+
```bash
|
| 31 |
+
python -m venv .env
|
| 32 |
+
```
|
| 33 |
+
|
| 34 |
+
仮想環境をアクティブにします:
|
| 35 |
+
|
| 36 |
+
```bash
|
| 37 |
+
source .env/bin/activate
|
| 38 |
+
```
|
| 39 |
+
|
| 40 |
+
🤗 Diffusers もまた 🤗 Transformers ライブラリに依存しており、以下のコマンドで両方をインストールできます:
|
| 41 |
+
|
| 42 |
+
<frameworkcontent>
|
| 43 |
+
<pt>
|
| 44 |
+
```bash
|
| 45 |
+
pip install diffusers["torch"] transformers
|
| 46 |
+
```
|
| 47 |
+
</pt>
|
| 48 |
+
<jax>
|
| 49 |
+
```bash
|
| 50 |
+
pip install diffusers["flax"] transformers
|
| 51 |
+
```
|
| 52 |
+
</jax>
|
| 53 |
+
</frameworkcontent>
|
| 54 |
+
|
| 55 |
+
## ソースからのインストール
|
| 56 |
+
|
| 57 |
+
ソースから🤗 Diffusersをインストールする前に、`torch`と🤗 Accelerateがインストールされていることを確認してください。
|
| 58 |
+
|
| 59 |
+
`torch`のインストールについては、`torch` [インストール](https://pytorch.org/get-started/locally/#start-locally)ガイドを参照してください。
|
| 60 |
+
|
| 61 |
+
🤗 Accelerateをインストールするには:
|
| 62 |
+
|
| 63 |
+
```bash
|
| 64 |
+
pip install accelerate
|
| 65 |
+
```
|
| 66 |
+
|
| 67 |
+
以下のコマンドでソースから🤗 Diffusersをインストールできます:
|
| 68 |
+
|
| 69 |
+
```bash
|
| 70 |
+
pip install git+https://github.com/huggingface/diffusers
|
| 71 |
+
```
|
| 72 |
+
|
| 73 |
+
このコマンドは最新の `stable` バージョンではなく、最先端の `main` バージョンをインストールします。
|
| 74 |
+
`main`バージョンは最新の開発に対応するのに便利です。
|
| 75 |
+
例えば、前回の公式リリース以降にバグが修正されたが、新しいリリースがまだリリースされていない場合などには都合がいいです。
|
| 76 |
+
しかし、これは `main` バージョンが常に安定しているとは限らないです。
|
| 77 |
+
私たちは `main` バージョンを運用し続けるよう努力しており、ほとんどの問題は通常数時間から1日以内に解決されます。
|
| 78 |
+
もし問題が発生した場合は、[Issue](https://github.com/huggingface/diffusers/issues/new/choose) を開いてください!
|
| 79 |
+
|
| 80 |
+
## 編集可能なインストール
|
| 81 |
+
|
| 82 |
+
以下の場合、編集可能なインストールが必要です:
|
| 83 |
+
|
| 84 |
+
* ソースコードの `main` バージョンを使用する。
|
| 85 |
+
* 🤗 Diffusers に貢献し、コードの変更をテストする必要がある場合。
|
| 86 |
+
|
| 87 |
+
リポジトリをクローンし、次のコマンドで 🤗 Diffusers をインストールしてください:
|
| 88 |
+
|
| 89 |
+
```bash
|
| 90 |
+
git clone https://github.com/huggingface/diffusers.git
|
| 91 |
+
cd diffusers
|
| 92 |
+
```
|
| 93 |
+
|
| 94 |
+
<frameworkcontent>
|
| 95 |
+
<pt>
|
| 96 |
+
```bash
|
| 97 |
+
pip install -e ".[torch]"
|
| 98 |
+
```
|
| 99 |
+
</pt>
|
| 100 |
+
<jax>
|
| 101 |
+
```bash
|
| 102 |
+
pip install -e ".[flax]"
|
| 103 |
+
```
|
| 104 |
+
</jax>
|
| 105 |
+
</frameworkcontent>
|
| 106 |
+
|
| 107 |
+
これらのコマンドは、リポジトリをクローンしたフォルダと Python のライブラリパスをリンクします。
|
| 108 |
+
Python は通常のライブラリパスに加えて、クローンしたフォルダの中を探すようになります。
|
| 109 |
+
例えば、Python パッケージが通常 `~/anaconda3/envs/main/lib/python3.10/site-packages/` にインストールされている場合、Python はクローンした `~/diffusers/` フォルダも同様に参照します。
|
| 110 |
+
|
| 111 |
+
<Tip warning={true}>
|
| 112 |
+
|
| 113 |
+
ライブラリを使い続けたい場合は、`diffusers`フォルダを残しておく必要があります。
|
| 114 |
+
|
| 115 |
+
</Tip>
|
| 116 |
+
|
| 117 |
+
これで、以下のコマンドで簡単にクローンを最新版の🤗 Diffusersにアップデートできます:
|
| 118 |
+
|
| 119 |
+
```bash
|
| 120 |
+
cd ~/diffusers/
|
| 121 |
+
git pull
|
| 122 |
+
```
|
| 123 |
+
|
| 124 |
+
Python環境��次の実行時に `main` バージョンの🤗 Diffusersを見つけます。
|
| 125 |
+
|
| 126 |
+
## テレメトリー・ロギングに関するお知らせ
|
| 127 |
+
|
| 128 |
+
このライブラリは `from_pretrained()` リクエスト中にデータを収集します。
|
| 129 |
+
このデータには Diffusers と PyTorch/Flax のバージョン、要求されたモデルやパイプラインクラスが含まれます。
|
| 130 |
+
また、Hubでホストされている場合は、事前に学習されたチェックポイントへのパスが含まれます。
|
| 131 |
+
この使用データは問題のデバッグや新機能の優先順位付けに役立ちます。
|
| 132 |
+
テレメトリーはHuggingFace Hubからモデルやパイプラインをロードするときのみ送信されます。ローカルでの使用中は収集されません。
|
| 133 |
+
|
| 134 |
+
我々は、すべての人が追加情報を共有したくないことを理解し、あなたのプライバシーを尊重します。
|
| 135 |
+
そのため、ターミナルから `DISABLE_TELEMETRY` 環境変数を設定することで、データ収集を無効にすることができます:
|
| 136 |
+
|
| 137 |
+
Linux/MacOSの場合
|
| 138 |
+
```bash
|
| 139 |
+
export DISABLE_TELEMETRY=YES
|
| 140 |
+
```
|
| 141 |
+
|
| 142 |
+
Windows の場合
|
| 143 |
+
```bash
|
| 144 |
+
set DISABLE_TELEMETRY=YES
|
| 145 |
+
```
|
tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ja/quicktour.md
ADDED
|
@@ -0,0 +1,316 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2024 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
[[open-in-colab]]
|
| 14 |
+
|
| 15 |
+
# 簡単な案内
|
| 16 |
+
|
| 17 |
+
拡散モデル(Diffusion Model)は、ランダムな正規分布から段階的にノイズ除去するように学習され、画像や音声などの目的のものを生成できます。これは生成AIに多大な関心を呼び起こしました。インターネット上で拡散によって生成された画像の例を見たことがあるでしょう。🧨 Diffusersは、誰もが拡散モデルに広くアクセスできるようにすることを目的としたライブラリです。
|
| 18 |
+
|
| 19 |
+
この案内では、開発者または日常的なユーザーに関わらず、🧨 Diffusers を紹介し、素早く目的のものを生成できるようにします!このライブラリには3つの主要コンポーネントがあります:
|
| 20 |
+
|
| 21 |
+
* [`DiffusionPipeline`]は事前に学習された拡散モデルからサンプルを迅速に生成するために設計された高レベルのエンドツーエンドクラス。
|
| 22 |
+
* 拡散システムを作成するためのビルディングブロックとして使用できる、人気のある事前学習された[モデル](./api/models)アーキテクチャとモジュール。
|
| 23 |
+
* 多くの異なる[スケジューラ](./api/schedulers/overview) - ノイズがどのようにトレーニングのために加えられるか、そして生成中にどのようにノイズ除去された画像を生成するかを制御するアルゴリズム。
|
| 24 |
+
|
| 25 |
+
この案内では、[`DiffusionPipeline`]を生成に使用する方法を紹介し、モデルとスケジューラを組み合わせて[`DiffusionPipeline`]の内部で起こっていることを再現する方法を説明します。
|
| 26 |
+
|
| 27 |
+
<Tip>
|
| 28 |
+
|
| 29 |
+
この案内は🧨 Diffusers [ノートブック](https://colab.research.google.com/github/huggingface/notebooks/blob/main/diffusers/diffusers_intro.ipynb)を簡略化したもので、すぐに使い始めることができます。Diffusers 🧨のゴール、設計哲学、コアAPIの詳細についてもっと知りたい方は、ノートブックをご覧ください!
|
| 30 |
+
|
| 31 |
+
</Tip>
|
| 32 |
+
|
| 33 |
+
始める前に必要なライブラリーがすべてインストールされていることを確認してください:
|
| 34 |
+
|
| 35 |
+
```py
|
| 36 |
+
# uncomment to install the necessary libraries in Colab
|
| 37 |
+
#!pip install --upgrade diffusers accelerate transformers
|
| 38 |
+
```
|
| 39 |
+
|
| 40 |
+
- [🤗 Accelerate](https://huggingface.co/docs/accelerate/index)生成とトレーニングのためのモデルのロードを高速化します
|
| 41 |
+
- [Stable Diffusion](https://huggingface.co/docs/diffusers/api/pipelines/stable_diffusion/overview)ような最も一般的な拡散モデルを実行するには、[🤗 Transformers](https://huggingface.co/docs/transformers/index)が必要です。
|
| 42 |
+
|
| 43 |
+
## 拡散パイプライン
|
| 44 |
+
|
| 45 |
+
[`DiffusionPipeline`]は事前学習された拡散システムを生成に使用する最も簡単な方法です。これはモデルとスケジューラを含むエンドツーエンドのシステムです。[`DiffusionPipeline`]は多くの作業/タスクにすぐに使用することができます。また、サポートされているタスクの完全なリストについては[🧨Diffusersの概要](./api/pipelines/overview#diffusers-summary)の表を参照してください。
|
| 46 |
+
|
| 47 |
+
| **タスク** | **説明** | **パイプライン**
|
| 48 |
+
|------------------------------|--------------------------------------------------------------------------------------------------------------|-----------------|
|
| 49 |
+
| Unconditional Image Generation | 正規分布から画像生成 | [unconditional_image_generation](./using-diffusers/unconditional_image_generation) |
|
| 50 |
+
| Text-Guided Image Generation | 文章から画像生成 | [conditional_image_generation](./using-diffusers/conditional_image_generation) |
|
| 51 |
+
| Text-Guided Image-to-Image Translation | 画像と文章から新たな画像生成 | [img2img](./using-diffusers/img2img) |
|
| 52 |
+
| Text-Guided Image-Inpainting | 画像、マスク、および文章が指定された場合に、画像のマスクされた部分を文章をもとに修復 | [inpaint](./using-diffusers/inpaint) |
|
| 53 |
+
| Text-Guided Depth-to-Image Translation | 文章と深度推定によって構造を保持しながら画像生成 | [depth2img](./using-diffusers/depth2img) |
|
| 54 |
+
|
| 55 |
+
まず、[`DiffusionPipeline`]のインスタンスを作成し、ダウンロードしたいパイプラインのチェックポイントを指定します。
|
| 56 |
+
この[`DiffusionPipeline`]はHugging Face Hubに保存されている任意の[チェックポイント](https://huggingface.co/models?library=diffusers&sort=downloads)を使用することができます。
|
| 57 |
+
この案内では、[`stable-diffusion-v1-5`](https://huggingface.co/stable-diffusion-v1-5/stable-diffusion-v1-5)チェックポイントでテキストから画像へ生成します。
|
| 58 |
+
|
| 59 |
+
<Tip warning={true}>
|
| 60 |
+
|
| 61 |
+
[Stable Diffusion]モデルについては、モデルを実行する前にまず[ライセンス](https://huggingface.co/spaces/CompVis/stable-diffusion-license)を注意深くお読みください。🧨 Diffusers は、攻撃的または有害なコンテンツを防ぐために [`safety_checker`](https://github.com/huggingface/diffusers/blob/main/src/diffusers/pipelines/stable_diffusion/safety_checker.py) を実装していますが、モデルの改良された画像生成機能により、潜在的に有害なコンテンツが生成される可能性があります。
|
| 62 |
+
|
| 63 |
+
</Tip>
|
| 64 |
+
|
| 65 |
+
モデルを[`~DiffusionPipeline.from_pretrained`]メソッドでロードします:
|
| 66 |
+
|
| 67 |
+
```python
|
| 68 |
+
>>> from diffusers import DiffusionPipeline
|
| 69 |
+
|
| 70 |
+
>>> pipeline = DiffusionPipeline.from_pretrained("stable-diffusion-v1-5/stable-diffusion-v1-5", use_safetensors=True)
|
| 71 |
+
```
|
| 72 |
+
[`DiffusionPipeline`]は全てのモデリング、トークン化、スケジューリングコンポーネントをダウンロードしてキャッシュします。Stable Diffusionパイプラインは[`UNet2DConditionModel`]と[`PNDMScheduler`]などで構成されています:
|
| 73 |
+
|
| 74 |
+
```py
|
| 75 |
+
>>> pipeline
|
| 76 |
+
StableDiffusionPipeline {
|
| 77 |
+
"_class_name": "StableDiffusionPipeline",
|
| 78 |
+
"_diffusers_version": "0.13.1",
|
| 79 |
+
...,
|
| 80 |
+
"scheduler": [
|
| 81 |
+
"diffusers",
|
| 82 |
+
"PNDMScheduler"
|
| 83 |
+
],
|
| 84 |
+
...,
|
| 85 |
+
"unet": [
|
| 86 |
+
"diffusers",
|
| 87 |
+
"UNet2DConditionModel"
|
| 88 |
+
],
|
| 89 |
+
"vae": [
|
| 90 |
+
"diffusers",
|
| 91 |
+
"AutoencoderKL"
|
| 92 |
+
]
|
| 93 |
+
}
|
| 94 |
+
```
|
| 95 |
+
|
| 96 |
+
このモデルはおよそ14億個のパラメータで構成されているため、GPU上でパイプラインを実行することを強く推奨します。
|
| 97 |
+
PyTorchと同じように、ジェネレータオブジェクトをGPUに移すことができます:
|
| 98 |
+
|
| 99 |
+
```python
|
| 100 |
+
>>> pipeline.to("cuda")
|
| 101 |
+
```
|
| 102 |
+
|
| 103 |
+
これで、文章を `pipeline` に渡して画像を生成し、ノイズ除去された画像にアクセスできるようになりました。デフォルトでは、画像出力は[`PIL.Image`](https://pillow.readthedocs.io/en/stable/reference/Image.html?highlight=image#the-image-class)オブジェクトでラップされます。
|
| 104 |
+
|
| 105 |
+
```python
|
| 106 |
+
>>> image = pipeline("An image of a squirrel in Picasso style").images[0]
|
| 107 |
+
>>> image
|
| 108 |
+
```
|
| 109 |
+
|
| 110 |
+
<div class="flex justify-center">
|
| 111 |
+
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/image_of_squirrel_painting.png"/>
|
| 112 |
+
</div>
|
| 113 |
+
|
| 114 |
+
`save`関数で画像を保存できます:
|
| 115 |
+
|
| 116 |
+
```python
|
| 117 |
+
>>> image.save("image_of_squirrel_painting.png")
|
| 118 |
+
```
|
| 119 |
+
|
| 120 |
+
### ローカルパイプライン
|
| 121 |
+
|
| 122 |
+
ローカルでパイプラインを使用することもできます。唯一の違いは、最初にウェイトをダウンロードする必要があることです:
|
| 123 |
+
|
| 124 |
+
```bash
|
| 125 |
+
!git lfs install
|
| 126 |
+
!git clone https://huggingface.co/stable-diffusion-v1-5/stable-diffusion-v1-5
|
| 127 |
+
```
|
| 128 |
+
|
| 129 |
+
保存したウェイトをパイプラインにロードします:
|
| 130 |
+
|
| 131 |
+
```python
|
| 132 |
+
>>> pipeline = DiffusionPipeline.from_pretrained("./stable-diffusion-v1-5", use_safetensors=True)
|
| 133 |
+
```
|
| 134 |
+
|
| 135 |
+
これで、上のセクションと同じようにパイプラインを動かすことができます。
|
| 136 |
+
|
| 137 |
+
### スケジューラの交換
|
| 138 |
+
|
| 139 |
+
スケジューラーによって、ノイズ除去のスピードや品質のトレードオフが異なります。どれが自分に最適かを知る最善の方法は、実際に試してみることです!Diffusers 🧨の主な機能の1つは、スケジューラを簡単に切り替えることができることです。例えば、デフォルトの[`PNDMScheduler`]を[`EulerDiscreteScheduler`]に置き換えるには、[`~diffusers.ConfigMixin.from_config`]メソッドでロードできます:
|
| 140 |
+
|
| 141 |
+
```py
|
| 142 |
+
>>> from diffusers import EulerDiscreteScheduler
|
| 143 |
+
|
| 144 |
+
>>> pipeline = DiffusionPipeline.from_pretrained("stable-diffusion-v1-5/stable-diffusion-v1-5", use_safetensors=True)
|
| 145 |
+
>>> pipeline.scheduler = EulerDiscreteScheduler.from_config(pipeline.scheduler.config)
|
| 146 |
+
```
|
| 147 |
+
|
| 148 |
+
新しいスケジューラを使って画像を生成し、その違いに気づくかどうか試してみてください!
|
| 149 |
+
|
| 150 |
+
次のセクションでは、[`DiffusionPipeline`]を構成するコンポーネント(モデルとスケジューラ)を詳しく見て、これらのコンポーネントを使って猫の画像を生成する方法を学びます。
|
| 151 |
+
|
| 152 |
+
## モデル
|
| 153 |
+
|
| 154 |
+
ほとんどのモデルはノイズの多いサンプルを取り、各タイムステップで*残りのノイズ*を予測します(他のモデルは前のサンプルを直接予測するか、速度��たは[`v-prediction`](https://github.com/huggingface/diffusers/blob/5e5ce13e2f89ac45a0066cb3f369462a3cf1d9ef/src/diffusers/schedulers/scheduling_ddim.py#L110)を予測するように学習します)。モデルを混ぜて他の拡散システムを作ることもできます。
|
| 155 |
+
|
| 156 |
+
モデルは[`~ModelMixin.from_pretrained`]メソッドで開始されます。このメソッドはモデルをローカルにキャッシュするので、次にモデルをロードするときに高速になります。この案内では、[`UNet2DModel`]をロードします。これは基本的な画像生成モデルであり、猫画像で学習されたチェックポイントを使います:
|
| 157 |
+
|
| 158 |
+
```py
|
| 159 |
+
>>> from diffusers import UNet2DModel
|
| 160 |
+
|
| 161 |
+
>>> repo_id = "google/ddpm-cat-256"
|
| 162 |
+
>>> model = UNet2DModel.from_pretrained(repo_id, use_safetensors=True)
|
| 163 |
+
```
|
| 164 |
+
|
| 165 |
+
モデルのパラメータにアクセスするには、`model.config` を呼び出せます:
|
| 166 |
+
|
| 167 |
+
```py
|
| 168 |
+
>>> model.config
|
| 169 |
+
```
|
| 170 |
+
|
| 171 |
+
モデル構成は🧊凍結🧊されたディクショナリであり、モデル作成後にこれらのパラメー タを変更することはできません。これは意図的なもので、最初にモデル・アーキテクチャを定義するために使用されるパラメータが同じままであることを保証します。他のパラメータは生成中に調整することができます。
|
| 172 |
+
|
| 173 |
+
最も重要なパラメータは以下の通りです:
|
| 174 |
+
|
| 175 |
+
* sample_size`: 入力サンプルの高さと幅。
|
| 176 |
+
* `in_channels`: 入力サンプルの入力チャンネル数。
|
| 177 |
+
* down_block_types` と `up_block_types`: UNet アーキテクチャを作成するために使用されるダウンサンプリングブロックとアップサンプリングブロックのタイプ。
|
| 178 |
+
* block_out_channels`: ダウンサンプリングブロックの出力チャンネル数。逆順でアップサンプリングブロックの入力チャンネル数にも使用されます。
|
| 179 |
+
* layer_per_block`: 各 UNet ブロックに含まれる ResNet ブロックの数。
|
| 180 |
+
|
| 181 |
+
このモデルを生成に使用するには、ランダムな画像の形の正規分布を作成します。このモデルは複数のランダムな正規分布を受け取ることができるため`batch`軸を入れます。入力チャンネル数に対応する`channel`軸も必要です。画像の高さと幅に対応する`sample_size`軸を持つ必要があります:
|
| 182 |
+
|
| 183 |
+
```py
|
| 184 |
+
>>> import torch
|
| 185 |
+
|
| 186 |
+
>>> torch.manual_seed(0)
|
| 187 |
+
|
| 188 |
+
>>> noisy_sample = torch.randn(1, model.config.in_channels, model.config.sample_size, model.config.sample_size)
|
| 189 |
+
>>> noisy_sample.shape
|
| 190 |
+
torch.Size([1, 3, 256, 256])
|
| 191 |
+
```
|
| 192 |
+
|
| 193 |
+
画像生成には、ノイズの多い画像と `timestep` をモデルに渡します。`timestep`は入力画像がどの程度ノイズが多いかを示します。これは、モデルが拡散プロセスにおける自分の位置を決定するのに役立ちます。モデルの出力を得るには `sample` メソッドを使用します:
|
| 194 |
+
|
| 195 |
+
```py
|
| 196 |
+
>>> with torch.no_grad():
|
| 197 |
+
... noisy_residual = model(sample=noisy_sample, timestep=2).sample
|
| 198 |
+
```
|
| 199 |
+
|
| 200 |
+
しかし、実際の例を生成するには、ノイズ除去プロセスをガイドするスケジューラが必要です。次のセクションでは、モデルをスケジューラと組み合わせる方法を学びます。
|
| 201 |
+
|
| 202 |
+
## スケジューラ
|
| 203 |
+
|
| 204 |
+
スケジューラは、モデルの出力(この場合は `noisy_residual` )が与えられたときに、ノイズの多いサンプルからノイズの少ないサンプルへの移行を管理します。
|
| 205 |
+
|
| 206 |
+
|
| 207 |
+
<Tip>
|
| 208 |
+
|
| 209 |
+
🧨 Diffusersは拡散システムを構築するためのツールボックスです。[`DiffusionPipeline`]は事前に構築された拡散システムを使い始めるのに便利な方法ですが、独自のモデルとスケジューラコンポーネントを個別に選択してカスタム拡散システムを構築することもできます。
|
| 210 |
+
|
| 211 |
+
</Tip>
|
| 212 |
+
|
| 213 |
+
この案内では、[`DDPMScheduler`]を[`~diffusers.ConfigMixin.from_config`]メソッドでインスタンス化します:
|
| 214 |
+
|
| 215 |
+
```py
|
| 216 |
+
>>> from diffusers import DDPMScheduler
|
| 217 |
+
|
| 218 |
+
>>> scheduler = DDPMScheduler.from_config(repo_id)
|
| 219 |
+
>>> scheduler
|
| 220 |
+
DDPMScheduler {
|
| 221 |
+
"_class_name": "DDPMScheduler",
|
| 222 |
+
"_diffusers_version": "0.13.1",
|
| 223 |
+
"beta_end": 0.02,
|
| 224 |
+
"beta_schedule": "linear",
|
| 225 |
+
"beta_start": 0.0001,
|
| 226 |
+
"clip_sample": true,
|
| 227 |
+
"clip_sample_range": 1.0,
|
| 228 |
+
"num_train_timesteps": 1000,
|
| 229 |
+
"prediction_type": "epsilon",
|
| 230 |
+
"trained_betas": null,
|
| 231 |
+
"variance_type": "fixed_small"
|
| 232 |
+
}
|
| 233 |
+
```
|
| 234 |
+
|
| 235 |
+
<Tip>
|
| 236 |
+
|
| 237 |
+
💡 スケジューラがどのようにコンフィギュレーションからインスタンス化されるかに注目してください。モデルとは異なり、スケジューラは学習可能な重みを持たず、パラメーターを持ちません!
|
| 238 |
+
|
| 239 |
+
</Tip>
|
| 240 |
+
|
| 241 |
+
最も重要なパラメータは以下の通りです:
|
| 242 |
+
|
| 243 |
+
* num_train_timesteps`: ノイズ除去処理の長さ、言い換えれば、ランダムな正規分布をデータサンプルに処理するのに必要なタイムステップ数です。
|
| 244 |
+
* `beta_schedule`: 生成とトレーニングに使用するノイズスケジュールのタイプ。
|
| 245 |
+
* `beta_start` と `beta_end`: ノイズスケジュールの開始値と終了値。
|
| 246 |
+
|
| 247 |
+
少しノイズの少ない画像を予測するには、スケジューラの [`~diffusers.DDPMScheduler.step`] メソッドに以下を渡します: モデルの出力、`timestep`、現在の `sample`。
|
| 248 |
+
|
| 249 |
+
```py
|
| 250 |
+
>>> less_noisy_sample = scheduler.step(model_output=noisy_residual, timestep=2, sample=noisy_sample).prev_sample
|
| 251 |
+
>>> less_noisy_sample.shape
|
| 252 |
+
```
|
| 253 |
+
|
| 254 |
+
`less_noisy_sample`は次の`timestep`に渡すことができ、そこでさらにノイズが少なくなります!
|
| 255 |
+
|
| 256 |
+
では、すべてをまとめて、ノイズ除去プロセス全体を視覚化してみましょう。
|
| 257 |
+
|
| 258 |
+
まず、ノイズ除去された画像を後処理して `PIL.Image` として表示する関数を作成します:
|
| 259 |
+
|
| 260 |
+
```py
|
| 261 |
+
>>> import PIL.Image
|
| 262 |
+
>>> import numpy as np
|
| 263 |
+
|
| 264 |
+
|
| 265 |
+
>>> def display_sample(sample, i):
|
| 266 |
+
... image_processed = sample.cpu().permute(0, 2, 3, 1)
|
| 267 |
+
... image_processed = (image_processed + 1.0) * 127.5
|
| 268 |
+
... image_processed = image_processed.numpy().astype(np.uint8)
|
| 269 |
+
|
| 270 |
+
... image_pil = PIL.Image.fromarray(image_processed[0])
|
| 271 |
+
... display(f"Image at step {i}")
|
| 272 |
+
... display(image_pil)
|
| 273 |
+
```
|
| 274 |
+
|
| 275 |
+
ノイズ除去処理を高速化するために入力とモデルをGPUに移します:
|
| 276 |
+
|
| 277 |
+
```py
|
| 278 |
+
>>> model.to("cuda")
|
| 279 |
+
>>> noisy_sample = noisy_sample.to("cuda")
|
| 280 |
+
```
|
| 281 |
+
|
| 282 |
+
ここで、ノイズが少なくなったサンプルの残りのノイズを予測するノイズ除去ループを作成し、スケジューラを使ってさらにノイズの少ないサンプルを計算します:
|
| 283 |
+
|
| 284 |
+
```py
|
| 285 |
+
>>> import tqdm
|
| 286 |
+
|
| 287 |
+
>>> sample = noisy_sample
|
| 288 |
+
|
| 289 |
+
>>> for i, t in enumerate(tqdm.tqdm(scheduler.timesteps)):
|
| 290 |
+
... # 1. predict noise residual
|
| 291 |
+
... with torch.no_grad():
|
| 292 |
+
... residual = model(sample, t).sample
|
| 293 |
+
|
| 294 |
+
... # 2. compute less noisy image and set x_t -> x_t-1
|
| 295 |
+
... sample = scheduler.step(residual, t, sample).prev_sample
|
| 296 |
+
|
| 297 |
+
... # 3. optionally look at image
|
| 298 |
+
... if (i + 1) % 50 == 0:
|
| 299 |
+
... display_sample(sample, i + 1)
|
| 300 |
+
```
|
| 301 |
+
|
| 302 |
+
何もないところから猫が生成されるのを、座って見てください!😻
|
| 303 |
+
|
| 304 |
+
<div class="flex justify-center">
|
| 305 |
+
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/diffusion-quicktour.png"/>
|
| 306 |
+
</div>
|
| 307 |
+
|
| 308 |
+
## 次のステップ
|
| 309 |
+
|
| 310 |
+
このクイックツアーで、🧨ディフューザーを使ったクールな画像をいくつか作成できたと思います!次のステップとして
|
| 311 |
+
|
| 312 |
+
* モデルをトレーニングまたは微調整については、[training](./tutorials/basic_training)チュートリアルを参照してください。
|
| 313 |
+
* 様々な使用例については、公式およびコミュニティの[training or finetuning scripts](https://github.com/huggingface/diffusers/tree/main/examples#-diffusers-examples)の例を参照してください。
|
| 314 |
+
* スケジューラのロード、アクセス、変更、比較については[Using different Schedulers](./using-diffusers/schedulers)ガイドを参照してください。
|
| 315 |
+
* プロンプトエンジニアリング、スピードとメモリの最適化、より高品質な画像を生成するためのヒントやトリックについては、[Stable Diffusion](./stable_diffusion)ガイドを参照してください。
|
| 316 |
+
* 🧨 Diffusers の高速化については、最適化された [PyTorch on a GPU](./optimization/fp16)のガイド、[Stable Diffusion on Apple Silicon (M1/M2)](./optimization/mps)と[ONNX Runtime](./optimization/onnx)を参照してください。
|
tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ja/stable_diffusion.md
ADDED
|
@@ -0,0 +1,260 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2024 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# 効果的で効率的な拡散モデル
|
| 14 |
+
|
| 15 |
+
[[open-in-colab]]
|
| 16 |
+
|
| 17 |
+
[`DiffusionPipeline`]を使って特定のスタイルで画像を生成したり、希望する画像を生成したりするのは難しいことです。多くの場合、[`DiffusionPipeline`]を何度か実行してからでないと満足のいく画像は得られません。しかし、何もないところから何かを生成するにはたくさんの計算が必要です。生成を何度も何度も実行する場合、特にたくさんの計算量が必要になります。
|
| 18 |
+
|
| 19 |
+
そのため、パイプラインから*計算*(速度)と*メモリ*(GPU RAM)の効率を最大限に引き出し、生成サイクル間の時間を短縮することで、より高速な反復処理を行えるようにすることが重要です。
|
| 20 |
+
|
| 21 |
+
このチュートリアルでは、[`DiffusionPipeline`]を用いて、より速く、より良い計算を行う方法を説明します。
|
| 22 |
+
|
| 23 |
+
まず、[`stable-diffusion-v1-5/stable-diffusion-v1-5`](https://huggingface.co/stable-diffusion-v1-5/stable-diffusion-v1-5)モデルをロードします:
|
| 24 |
+
|
| 25 |
+
```python
|
| 26 |
+
from diffusers import DiffusionPipeline
|
| 27 |
+
|
| 28 |
+
model_id = "stable-diffusion-v1-5/stable-diffusion-v1-5"
|
| 29 |
+
pipeline = DiffusionPipeline.from_pretrained(model_id, use_safetensors=True)
|
| 30 |
+
```
|
| 31 |
+
|
| 32 |
+
ここで使用するプロンプトの例は年老いた戦士の長の肖像画ですが、ご自由に変更してください:
|
| 33 |
+
|
| 34 |
+
```python
|
| 35 |
+
prompt = "portrait photo of a old warrior chief"
|
| 36 |
+
```
|
| 37 |
+
|
| 38 |
+
## Speed
|
| 39 |
+
|
| 40 |
+
<Tip>
|
| 41 |
+
|
| 42 |
+
💡 GPUを利用できない場合は、[Colab](https://colab.research.google.com/)のようなGPUプロバイダーから無料で利用できます!
|
| 43 |
+
|
| 44 |
+
</Tip>
|
| 45 |
+
|
| 46 |
+
画像生成を高速化する最も簡単な方法の1つは、PyTorchモジュールと同じようにGPU上にパイプラインを配置することです:
|
| 47 |
+
|
| 48 |
+
```python
|
| 49 |
+
pipeline = pipeline.to("cuda")
|
| 50 |
+
```
|
| 51 |
+
|
| 52 |
+
同じイメージを使って改良できるようにするには、[`Generator`](https://pytorch.org/docs/stable/generated/torch.Generator.html)を使い、[reproducibility](./using-diffusers/reusing_seeds)の種を設定します:
|
| 53 |
+
|
| 54 |
+
```python
|
| 55 |
+
import torch
|
| 56 |
+
|
| 57 |
+
generator = torch.Generator("cuda").manual_seed(0)
|
| 58 |
+
```
|
| 59 |
+
|
| 60 |
+
これで画像を生成できます:
|
| 61 |
+
|
| 62 |
+
```python
|
| 63 |
+
image = pipeline(prompt, generator=generator).images[0]
|
| 64 |
+
image
|
| 65 |
+
```
|
| 66 |
+
|
| 67 |
+
<div class="flex justify-center">
|
| 68 |
+
<img src="https://huggingface.co/datasets/diffusers/docs-images/resolve/main/stable_diffusion_101/sd_101_1.png">
|
| 69 |
+
</div>
|
| 70 |
+
|
| 71 |
+
この処理にはT4 GPUで~30秒かかりました(割り当てられているGPUがT4より優れている場合はもっと速いかもしれません)。デフォルトでは、[`DiffusionPipeline`]は完全な`float32`精度で生成を50ステップ実行します。float16`のような低い精度に変更するか、推論ステップ数を減らすことで高速化することができます。
|
| 72 |
+
|
| 73 |
+
まずは `float16` でモデルをロードして画像を生成してみましょう:
|
| 74 |
+
|
| 75 |
+
```python
|
| 76 |
+
import torch
|
| 77 |
+
|
| 78 |
+
pipeline = DiffusionPipeline.from_pretrained(model_id, torch_dtype=torch.float16, use_safetensors=True)
|
| 79 |
+
pipeline = pipeline.to("cuda")
|
| 80 |
+
generator = torch.Generator("cuda").manual_seed(0)
|
| 81 |
+
image = pipeline(prompt, generator=generator).images[0]
|
| 82 |
+
image
|
| 83 |
+
```
|
| 84 |
+
|
| 85 |
+
<div class="flex justify-center">
|
| 86 |
+
<img src="https://huggingface.co/datasets/diffusers/docs-images/resolve/main/stable_diffusion_101/sd_101_2.png">
|
| 87 |
+
</div>
|
| 88 |
+
|
| 89 |
+
今回、画像生成にかかった時間はわずか11秒で、以前より3倍近く速くなりました!
|
| 90 |
+
|
| 91 |
+
<Tip>
|
| 92 |
+
|
| 93 |
+
💡 パイプラインは常に `float16` で実行することを強くお勧めします。
|
| 94 |
+
|
| 95 |
+
</Tip>
|
| 96 |
+
|
| 97 |
+
生成ステップ数を減らすという方法もあります。より効率的なスケジューラを選択することで、出力品質を犠牲にすることなくステップ数を減らすことができます。`compatibles`メソッドを呼び出すことで、[`DiffusionPipeline`]の現在のモデルと互換性のあるスケジューラを見つけることができます:
|
| 98 |
+
|
| 99 |
+
```python
|
| 100 |
+
pipeline.scheduler.compatibles
|
| 101 |
+
[
|
| 102 |
+
diffusers.schedulers.scheduling_lms_discrete.LMSDiscreteScheduler,
|
| 103 |
+
diffusers.schedulers.scheduling_unipc_multistep.UniPCMultistepScheduler,
|
| 104 |
+
diffusers.schedulers.scheduling_k_dpm_2_discrete.KDPM2DiscreteScheduler,
|
| 105 |
+
diffusers.schedulers.scheduling_deis_multistep.DEISMultistepScheduler,
|
| 106 |
+
diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler,
|
| 107 |
+
diffusers.schedulers.scheduling_dpmsolver_multistep.DPMSolverMultistepScheduler,
|
| 108 |
+
diffusers.schedulers.scheduling_ddpm.DDPMScheduler,
|
| 109 |
+
diffusers.schedulers.scheduling_dpmsolver_singlestep.DPMSolverSinglestepScheduler,
|
| 110 |
+
diffusers.schedulers.scheduling_k_dpm_2_ancestral_discrete.KDPM2AncestralDiscreteScheduler,
|
| 111 |
+
diffusers.schedulers.scheduling_heun_discrete.HeunDiscreteScheduler,
|
| 112 |
+
diffusers.schedulers.scheduling_pndm.PNDMScheduler,
|
| 113 |
+
diffusers.schedulers.scheduling_euler_ancestral_discrete.EulerAncestralDiscreteScheduler,
|
| 114 |
+
diffusers.schedulers.scheduling_ddim.DDIMScheduler,
|
| 115 |
+
]
|
| 116 |
+
```
|
| 117 |
+
|
| 118 |
+
Stable Diffusionモデルはデフォルトで[`PNDMScheduler`]を使用します。このスケジューラは通常~50の推論ステップを必要としますが、[`DPMSolverMultistepScheduler`]のような高性能なスケジューラでは~20または25の推論ステップで済みます。[`ConfigMixin.from_config`]メソッドを使用すると、新しいスケジューラをロードすることができます:
|
| 119 |
+
|
| 120 |
+
```python
|
| 121 |
+
from diffusers import DPMSolverMultistepScheduler
|
| 122 |
+
|
| 123 |
+
pipeline.scheduler = DPMSolverMultistepScheduler.from_config(pipeline.scheduler.config)
|
| 124 |
+
```
|
| 125 |
+
|
| 126 |
+
ここで `num_inference_steps` を20に設定します:
|
| 127 |
+
|
| 128 |
+
```python
|
| 129 |
+
generator = torch.Generator("cuda").manual_seed(0)
|
| 130 |
+
image = pipeline(prompt, generator=generator, num_inference_steps=20).images[0]
|
| 131 |
+
image
|
| 132 |
+
```
|
| 133 |
+
|
| 134 |
+
<div class="flex justify-center">
|
| 135 |
+
<img src="https://huggingface.co/datasets/diffusers/docs-images/resolve/main/stable_diffusion_101/sd_101_3.png">
|
| 136 |
+
</div>
|
| 137 |
+
|
| 138 |
+
推論時間をわずか4秒に短縮することに成功した!⚡️
|
| 139 |
+
|
| 140 |
+
## メモリー
|
| 141 |
+
|
| 142 |
+
パイプラインのパフォーマンスを向上させるもう1つの鍵は、消費メモリを少なくすることです。一度に生成できる画像の数を確認する最も簡単な方法は、`OutOfMemoryError`(OOM)が発生するまで、さまざまなバッチサイズを試してみることです。
|
| 143 |
+
|
| 144 |
+
文章と `Generators` のリストから画像のバッチを生成する関数を作成します。各 `Generator` にシードを割り当てて、良い結果が得られた場合に再利用できるようにします。
|
| 145 |
+
|
| 146 |
+
```python
|
| 147 |
+
def get_inputs(batch_size=1):
|
| 148 |
+
generator = [torch.Generator("cuda").manual_seed(i) for i in range(batch_size)]
|
| 149 |
+
prompts = batch_size * [prompt]
|
| 150 |
+
num_inference_steps = 20
|
| 151 |
+
|
| 152 |
+
return {"prompt": prompts, "generator": generator, "num_inference_steps": num_inference_steps}
|
| 153 |
+
```
|
| 154 |
+
|
| 155 |
+
`batch_size=4`で開始し、どれだけメモリを消費したかを確認します:
|
| 156 |
+
|
| 157 |
+
```python
|
| 158 |
+
from diffusers.utils import make_image_grid
|
| 159 |
+
|
| 160 |
+
images = pipeline(**get_inputs(batch_size=4)).images
|
| 161 |
+
make_image_grid(images, 2, 2)
|
| 162 |
+
```
|
| 163 |
+
|
| 164 |
+
大容量のRAMを搭載したGPUでない限り、上記のコードはおそらく`OOM`エラーを返したはずです!メモリの大半はクロスアテンションレイヤーが占めています。この処理をバッチで実行する代わりに、逐次実行することでメモリを大幅に節約できます。必要なのは、[`~DiffusionPipeline.enable_attention_slicing`]関数を使用することだけです:
|
| 165 |
+
|
| 166 |
+
```python
|
| 167 |
+
pipeline.enable_attention_slicing()
|
| 168 |
+
```
|
| 169 |
+
|
| 170 |
+
今度は`batch_size`を8にしてみてください!
|
| 171 |
+
|
| 172 |
+
```python
|
| 173 |
+
images = pipeline(**get_inputs(batch_size=8)).images
|
| 174 |
+
make_image_grid(images, rows=2, cols=4)
|
| 175 |
+
```
|
| 176 |
+
|
| 177 |
+
<div class="flex justify-center">
|
| 178 |
+
<img src="https://huggingface.co/datasets/diffusers/docs-images/resolve/main/stable_diffusion_101/sd_101_5.png">
|
| 179 |
+
</div>
|
| 180 |
+
|
| 181 |
+
以前は4枚の画像のバッチを生成することさえできませんでしたが、今では8枚の画像のバッチを1枚あたり~3.5秒で生成できます!これはおそらく、品質を犠牲にすることなくT4 GPUでできる最速の処理速度です。
|
| 182 |
+
|
| 183 |
+
## 品質
|
| 184 |
+
|
| 185 |
+
前の2つのセクションでは、`fp16` を使ってパイプラインの速度を最適化する方法、よりパフォーマン スなスケジューラーを使って生成ステップ数を減らす方法、アテンションスライスを有効 にしてメモリ消費量を減らす方法について学びました。今度は、生成される画像の品質を向上させる方法に焦点を当てます。
|
| 186 |
+
|
| 187 |
+
### より良いチェックポイント
|
| 188 |
+
|
| 189 |
+
最も単純なステップは、より良いチェックポイントを使うことです。Stable Diffusionモデルは良い出発点であり、公式発表以来、いくつかの改良版もリリースされています。しかし、新しいバージョンを使ったからといって、自動的に良い結果が得られるわけではありません。最良の結果を得るためには、自分でさまざまなチェックポイントを試してみたり、ちょっとした研究([ネガティブプロンプト](https://minimaxir.com/2022/11/stable-diffusion-negative-prompt/)の使用など)をしたりする必要がありま���。
|
| 190 |
+
|
| 191 |
+
この分野が成長するにつれて、特定のスタイルを生み出すために微調整された、より質の高いチェックポイントが増えています。[Hub](https://huggingface.co/models?library=diffusers&sort=downloads)や[Diffusers Gallery](https://huggingface.co/spaces/huggingface-projects/diffusers-gallery)を探索して、興味のあるものを見つけてみてください!
|
| 192 |
+
|
| 193 |
+
### より良いパイプラインコンポーネント
|
| 194 |
+
|
| 195 |
+
現在のパイプラインコンポーネントを新しいバージョンに置き換えてみることもできます。Stability AIが提供する最新の[autodecoder](https://huggingface.co/stabilityai/stable-diffusion-2-1/tree/main/vae)をパイプラインにロードし、画像を生成してみましょう:
|
| 196 |
+
|
| 197 |
+
```python
|
| 198 |
+
from diffusers import AutoencoderKL
|
| 199 |
+
|
| 200 |
+
vae = AutoencoderKL.from_pretrained("stabilityai/sd-vae-ft-mse", torch_dtype=torch.float16).to("cuda")
|
| 201 |
+
pipeline.vae = vae
|
| 202 |
+
images = pipeline(**get_inputs(batch_size=8)).images
|
| 203 |
+
make_image_grid(images, rows=2, cols=4)
|
| 204 |
+
```
|
| 205 |
+
|
| 206 |
+
<div class="flex justify-center">
|
| 207 |
+
<img src="https://huggingface.co/datasets/diffusers/docs-images/resolve/main/stable_diffusion_101/sd_101_6.png">
|
| 208 |
+
</div>
|
| 209 |
+
|
| 210 |
+
### より良いプロンプト・エンジニアリング
|
| 211 |
+
|
| 212 |
+
画像を生成するために使用する文章は、*プロンプトエンジニアリング*と呼ばれる分野を作られるほど、非常に重要です。プロンプト・エンジニアリングで考慮すべき点は以下の通りです:
|
| 213 |
+
|
| 214 |
+
- 生成したい画像やその類似画像は、インターネット上にどのように保存されているか?
|
| 215 |
+
- 私が望むスタイルにモデルを誘導するために、どのような追加詳細を与えるべきか?
|
| 216 |
+
|
| 217 |
+
このことを念頭に置いて、プロンプトに色やより質の高いディテールを含めるように改良してみましょう:
|
| 218 |
+
|
| 219 |
+
```python
|
| 220 |
+
prompt += ", tribal panther make up, blue on red, side profile, looking away, serious eyes"
|
| 221 |
+
prompt += " 50mm portrait photography, hard rim lighting photography--beta --ar 2:3 --beta --upbeta"
|
| 222 |
+
```
|
| 223 |
+
|
| 224 |
+
新しいプロンプトで画像のバッチを生成しましょう:
|
| 225 |
+
|
| 226 |
+
```python
|
| 227 |
+
images = pipeline(**get_inputs(batch_size=8)).images
|
| 228 |
+
make_image_grid(images, rows=2, cols=4)
|
| 229 |
+
```
|
| 230 |
+
|
| 231 |
+
<div class="flex justify-center">
|
| 232 |
+
<img src="https://huggingface.co/datasets/diffusers/docs-images/resolve/main/stable_diffusion_101/sd_101_7.png">
|
| 233 |
+
</div>
|
| 234 |
+
|
| 235 |
+
かなりいいです!種が`1`の`Generator`に対応する2番目の画像に、被写体の年齢に関するテキストを追加して、もう少し手を加えてみましょう:
|
| 236 |
+
|
| 237 |
+
```python
|
| 238 |
+
prompts = [
|
| 239 |
+
"portrait photo of the oldest warrior chief, tribal panther make up, blue on red, side profile, looking away, serious eyes 50mm portrait photography, hard rim lighting photography--beta --ar 2:3 --beta --upbeta",
|
| 240 |
+
"portrait photo of a old warrior chief, tribal panther make up, blue on red, side profile, looking away, serious eyes 50mm portrait photography, hard rim lighting photography--beta --ar 2:3 --beta --upbeta",
|
| 241 |
+
"portrait photo of a warrior chief, tribal panther make up, blue on red, side profile, looking away, serious eyes 50mm portrait photography, hard rim lighting photography--beta --ar 2:3 --beta --upbeta",
|
| 242 |
+
"portrait photo of a young warrior chief, tribal panther make up, blue on red, side profile, looking away, serious eyes 50mm portrait photography, hard rim lighting photography--beta --ar 2:3 --beta --upbeta",
|
| 243 |
+
]
|
| 244 |
+
|
| 245 |
+
generator = [torch.Generator("cuda").manual_seed(1) for _ in range(len(prompts))]
|
| 246 |
+
images = pipeline(prompt=prompts, generator=generator, num_inference_steps=25).images
|
| 247 |
+
make_image_grid(images, 2, 2)
|
| 248 |
+
```
|
| 249 |
+
|
| 250 |
+
<div class="flex justify-center">
|
| 251 |
+
<img src="https://huggingface.co/datasets/diffusers/docs-images/resolve/main/stable_diffusion_101/sd_101_8.png">
|
| 252 |
+
</div>
|
| 253 |
+
|
| 254 |
+
## 次のステップ
|
| 255 |
+
|
| 256 |
+
このチュートリアルでは、[`DiffusionPipeline`]を最適化して計算効率とメモリ効率を向上させ、生成される出力の品質を向上させる方法を学びました。パイプラインをさらに高速化することに興味があれば、以下のリソースを参照してください:
|
| 257 |
+
|
| 258 |
+
- [PyTorch 2.0](./optimization/torch2.0)と[`torch.compile`](https://pytorch.org/docs/stable/generated/torch.compile.html)がどのように生成速度を5-300%高速化できるかを学んでください。A100 GPUの場合、画像生成は最大50%速くなります!
|
| 259 |
+
- PyTorch 2が使えない場合は、[xFormers](./optimization/xformers)をインストールすることをお勧めします。このライブラリのメモリ効率の良いアテンションメカニズムは PyTorch 1.13.1 と相性が良く、高速化とメモリ消費量の削減を同時に実現します。
|
| 260 |
+
- モデルのオフロードなど、その他の最適化テクニックは [this guide](./optimization/fp16) でカバーされています。
|
tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ja/tutorials/autopipeline.md
ADDED
|
@@ -0,0 +1,168 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2024 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# AutoPipeline
|
| 14 |
+
|
| 15 |
+
Diffusersは様々なタスクをこなすことができ、テキストから画像、画像から画像、画像の修復など、複数のタスクに対して同じように事前学習された重みを再利用することができます。しかし、ライブラリや拡散モデルに慣れていない場合、どのタスクにどのパイプラインを使えばいいのかがわかりにくいかもしれません。例えば、 [stable-diffusion-v1-5/stable-diffusion-v1-5](https://huggingface.co/stable-diffusion-v1-5/stable-diffusion-v1-5) チェックポイントをテキストから画像に変換するために使用している場合、それぞれ[`StableDiffusionImg2ImgPipeline`]クラスと[`StableDiffusionInpaintPipeline`]クラスでチェックポイントをロードすることで、画像から画像や画像の修復にも使えることを知らない可能性もあります。
|
| 16 |
+
|
| 17 |
+
`AutoPipeline` クラスは、🤗 Diffusers の様々なパイプラインをよりシンプルするために設計されています。この汎用的でタスク重視のパイプラインによってタスクそのものに集中することができます。`AutoPipeline` は、使用するべき正しいパイプラインクラスを自動的に検出するため、特定のパイプラインクラス名を知らなくても、タスクのチェックポイントを簡単にロードできます。
|
| 18 |
+
|
| 19 |
+
<Tip>
|
| 20 |
+
|
| 21 |
+
どのタスクがサポートされているかは、[AutoPipeline](../api/pipelines/auto_pipeline) のリファレンスをご覧ください。現在、text-to-image、image-to-image、inpaintingをサポートしています。
|
| 22 |
+
|
| 23 |
+
</Tip>
|
| 24 |
+
|
| 25 |
+
このチュートリアルでは、`AutoPipeline` を使用して、事前に学習された重みが与えられたときに、特定のタスクを読み込むためのパイプラインクラスを自動的に推測する方法を示します。
|
| 26 |
+
|
| 27 |
+
## タスクに合わせてAutoPipeline を選択する
|
| 28 |
+
まずはチェックポイントを選ぶことから始めましょう。例えば、 [stable-diffusion-v1-5/stable-diffusion-v1-5](https://huggingface.co/stable-diffusion-v1-5/stable-diffusion-v1-5) チェックポイントでテキストから画像への変換したいなら、[`AutoPipelineForText2Image`]を使います:
|
| 29 |
+
|
| 30 |
+
```py
|
| 31 |
+
from diffusers import AutoPipelineForText2Image
|
| 32 |
+
import torch
|
| 33 |
+
|
| 34 |
+
pipeline = AutoPipelineForText2Image.from_pretrained(
|
| 35 |
+
"stable-diffusion-v1-5/stable-diffusion-v1-5", torch_dtype=torch.float16, use_safetensors=True
|
| 36 |
+
).to("cuda")
|
| 37 |
+
prompt = "peasant and dragon combat, wood cutting style, viking era, bevel with rune"
|
| 38 |
+
|
| 39 |
+
image = pipeline(prompt, num_inference_steps=25).images[0]
|
| 40 |
+
image
|
| 41 |
+
```
|
| 42 |
+
|
| 43 |
+
<div class="flex justify-center">
|
| 44 |
+
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/autopipeline-text2img.png" alt="generated image of peasant fighting dragon in wood cutting style"/>
|
| 45 |
+
</div>
|
| 46 |
+
|
| 47 |
+
[`AutoPipelineForText2Image`] を具体的に見ていきましょう:
|
| 48 |
+
|
| 49 |
+
1. [`model_index.json`](https://huggingface.co/stable-diffusion-v1-5/stable-diffusion-v1-5/blob/main/model_index.json) ファイルから `"stable-diffusion"` クラスを自動的に検出します。
|
| 50 |
+
2. `"stable-diffusion"` のクラス名に基づいて、テキストから画像へ変換する [`StableDiffusionPipeline`] を読み込みます。
|
| 51 |
+
|
| 52 |
+
同様に、画像から画像へ変換する場合、[`AutoPipelineForImage2Image`] は `model_index.json` ファイルから `"stable-diffusion"` チェックポイントを検出し、対応する [`StableDiffusionImg2ImgPipeline`] を読み込みます。また、入力画像にノイズの量やバリエーションの追加を決めるための強さなど、パイプラインクラスに固有の追加引数を渡すこともできます:
|
| 53 |
+
|
| 54 |
+
```py
|
| 55 |
+
from diffusers import AutoPipelineForImage2Image
|
| 56 |
+
import torch
|
| 57 |
+
import requests
|
| 58 |
+
from PIL import Image
|
| 59 |
+
from io import BytesIO
|
| 60 |
+
|
| 61 |
+
pipeline = AutoPipelineForImage2Image.from_pretrained(
|
| 62 |
+
"stable-diffusion-v1-5/stable-diffusion-v1-5",
|
| 63 |
+
torch_dtype=torch.float16,
|
| 64 |
+
use_safetensors=True,
|
| 65 |
+
).to("cuda")
|
| 66 |
+
prompt = "a portrait of a dog wearing a pearl earring"
|
| 67 |
+
|
| 68 |
+
url = "https://upload.wikimedia.org/wikipedia/commons/thumb/0/0f/1665_Girl_with_a_Pearl_Earring.jpg/800px-1665_Girl_with_a_Pearl_Earring.jpg"
|
| 69 |
+
|
| 70 |
+
response = requests.get(url)
|
| 71 |
+
image = Image.open(BytesIO(response.content)).convert("RGB")
|
| 72 |
+
image.thumbnail((768, 768))
|
| 73 |
+
|
| 74 |
+
image = pipeline(prompt, image, num_inference_steps=200, strength=0.75, guidance_scale=10.5).images[0]
|
| 75 |
+
image
|
| 76 |
+
```
|
| 77 |
+
|
| 78 |
+
<div class="flex justify-center">
|
| 79 |
+
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/autopipeline-img2img.png" alt="generated image of a vermeer portrait of a dog wearing a pearl earring"/>
|
| 80 |
+
</div>
|
| 81 |
+
|
| 82 |
+
また、画像の修復を行いたい場合は、 [`AutoPipelineForInpainting`] が、同様にベースとなる[`StableDiffusionInpaintPipeline`]クラスを読み込みます:
|
| 83 |
+
|
| 84 |
+
```py
|
| 85 |
+
from diffusers import AutoPipelineForInpainting
|
| 86 |
+
from diffusers.utils import load_image
|
| 87 |
+
import torch
|
| 88 |
+
|
| 89 |
+
pipeline = AutoPipelineForInpainting.from_pretrained(
|
| 90 |
+
"stabilityai/stable-diffusion-xl-base-1.0", torch_dtype=torch.float16, use_safetensors=True
|
| 91 |
+
).to("cuda")
|
| 92 |
+
|
| 93 |
+
img_url = "https://raw.githubusercontent.com/CompVis/latent-diffusion/main/data/inpainting_examples/overture-creations-5sI6fQgYIuo.png"
|
| 94 |
+
mask_url = "https://raw.githubusercontent.com/CompVis/latent-diffusion/main/data/inpainting_examples/overture-creations-5sI6fQgYIuo_mask.png"
|
| 95 |
+
|
| 96 |
+
init_image = load_image(img_url).convert("RGB")
|
| 97 |
+
mask_image = load_image(mask_url).convert("RGB")
|
| 98 |
+
|
| 99 |
+
prompt = "A majestic tiger sitting on a bench"
|
| 100 |
+
image = pipeline(prompt, image=init_image, mask_image=mask_image, num_inference_steps=50, strength=0.80).images[0]
|
| 101 |
+
image
|
| 102 |
+
```
|
| 103 |
+
|
| 104 |
+
<div class="flex justify-center">
|
| 105 |
+
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/autopipeline-inpaint.png" alt="generated image of a tiger sitting on a bench"/>
|
| 106 |
+
</div>
|
| 107 |
+
|
| 108 |
+
サポートされていないチェックポイントを読み込もうとすると、エラーになります:
|
| 109 |
+
|
| 110 |
+
```py
|
| 111 |
+
from diffusers import AutoPipelineForImage2Image
|
| 112 |
+
import torch
|
| 113 |
+
|
| 114 |
+
pipeline = AutoPipelineForImage2Image.from_pretrained(
|
| 115 |
+
"openai/shap-e-img2img", torch_dtype=torch.float16, use_safetensors=True
|
| 116 |
+
)
|
| 117 |
+
"ValueError: AutoPipeline can't find a pipeline linked to ShapEImg2ImgPipeline for None"
|
| 118 |
+
```
|
| 119 |
+
|
| 120 |
+
## 複数のパイプラインを使用する
|
| 121 |
+
|
| 122 |
+
いくつかのワークフローや多くのパイプラインを読み込む場合、不要なメモリを使ってしまう再読み込みをするよりも、チェックポイントから同じコンポーネントを再利用する方がメモリ効率が良いです。たとえば、テキストから画像への変換にチェックポイントを使い、画像から画像への変換にまたチェックポイントを使いたい場合、[from_pipe()](https://huggingface.co/docs/diffusers/v0.25.1/en/api/pipelines/auto_pipeline#diffusers.AutoPipelineForImage2Image.from_pipe) メソッドを使用します。このメソッドは、以前読み込まれたパイプラインのコンポーネントを使うことで追加のメモリを消費することなく、新しいパイプラインを作成します。
|
| 123 |
+
|
| 124 |
+
[from_pipe()](https://huggingface.co/docs/diffusers/v0.25.1/en/api/pipelines/auto_pipeline#diffusers.AutoPipelineForImage2Image.from_pipe) メソッドは、元のパイプラインクラスを検出し、実行したいタスクに対応する新しいパイプラインクラスにマッピングします。例えば、テキストから画像への`"stable-diffusion"` クラスのパイプラインを読み込む場合:
|
| 125 |
+
|
| 126 |
+
```py
|
| 127 |
+
from diffusers import AutoPipelineForText2Image, AutoPipelineForImage2Image
|
| 128 |
+
import torch
|
| 129 |
+
|
| 130 |
+
pipeline_text2img = AutoPipelineForText2Image.from_pretrained(
|
| 131 |
+
"stable-diffusion-v1-5/stable-diffusion-v1-5", torch_dtype=torch.float16, use_safetensors=True
|
| 132 |
+
)
|
| 133 |
+
print(type(pipeline_text2img))
|
| 134 |
+
"<class 'diffusers.pipelines.stable_diffusion.pipeline_stable_diffusion.StableDiffusionPipeline'>"
|
| 135 |
+
```
|
| 136 |
+
|
| 137 |
+
そして、[from_pipe()] (https://huggingface.co/docs/diffusers/v0.25.1/en/api/pipelines/auto_pipeline#diffusers.AutoPipelineForImage2Image.from_pipe)は、もとの`"stable-diffusion"` パイプラインのクラスである [`StableDiffusionImg2ImgPipeline`] にマップします:
|
| 138 |
+
|
| 139 |
+
```py
|
| 140 |
+
pipeline_img2img = AutoPipelineForImage2Image.from_pipe(pipeline_text2img)
|
| 141 |
+
print(type(pipeline_img2img))
|
| 142 |
+
"<class 'diffusers.pipelines.stable_diffusion.pipeline_stable_diffusion_img2img.StableDiffusionImg2ImgPipeline'>"
|
| 143 |
+
```
|
| 144 |
+
元のパイプラインにオプションとして引数(セーフティチェッカーの無効化など)を渡した場合、この引数も新しいパイプラインに渡されます:
|
| 145 |
+
|
| 146 |
+
```py
|
| 147 |
+
from diffusers import AutoPipelineForText2Image, AutoPipelineForImage2Image
|
| 148 |
+
import torch
|
| 149 |
+
|
| 150 |
+
pipeline_text2img = AutoPipelineForText2Image.from_pretrained(
|
| 151 |
+
"stable-diffusion-v1-5/stable-diffusion-v1-5",
|
| 152 |
+
torch_dtype=torch.float16,
|
| 153 |
+
use_safetensors=True,
|
| 154 |
+
requires_safety_checker=False,
|
| 155 |
+
).to("cuda")
|
| 156 |
+
|
| 157 |
+
pipeline_img2img = AutoPipelineForImage2Image.from_pipe(pipeline_text2img)
|
| 158 |
+
print(pipeline_img2img.config.requires_safety_checker)
|
| 159 |
+
"False"
|
| 160 |
+
```
|
| 161 |
+
|
| 162 |
+
新しいパイプラインの動作を変更したい場合は、元のパイプラインの引数や設定を上書きするこ���ができます。例えば、セーフティチェッカーをオンに戻し、`strength` 引数を追加します:
|
| 163 |
+
|
| 164 |
+
```py
|
| 165 |
+
pipeline_img2img = AutoPipelineForImage2Image.from_pipe(pipeline_text2img, requires_safety_checker=True, strength=0.3)
|
| 166 |
+
print(pipeline_img2img.config.requires_safety_checker)
|
| 167 |
+
"True"
|
| 168 |
+
```
|
tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ja/tutorials/tutorial_overview.md
ADDED
|
@@ -0,0 +1,23 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2024 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Overview
|
| 14 |
+
|
| 15 |
+
ようこそ 🧨Diffusersへ!拡散モデル(diffusion models)や生成AIの初心者で、さらに学びたいのであれば、このチュートリアルが最適です。この初心者向けのチュートリアルは、拡散モデルについて丁寧に解説し、ライブラリの基礎(核となるコンポーネントと 🧨Diffusersの使用方法)を理解することを目的としています。
|
| 16 |
+
|
| 17 |
+
まず、推論のためのパイプラインを使って、素早く生成する方法を学んでいきます。次に、独自の拡散システムを構築するためのモジュラーツールボックスとしてライブラリをどのように使えば良いかを理解するために、そのパイプラインを分解してみましょう。次のレッスンでは、あなたの欲しいものを生成できるように拡散モデルをトレーニングする方法を学びましょう。
|
| 18 |
+
|
| 19 |
+
このチュートリアルがすべて完了したら、ライブラリを自分で調べ、自分のプロジェクトやアプリケーションにどのように使えるかを知るために必要なスキルを身につけることができます。
|
| 20 |
+
|
| 21 |
+
そして、 [Discord](https://discord.com/invite/JfAtkvEtRb) や [forums](https://discuss.huggingface.co/c/discussion-related-to-httpsgithubcomhuggingfacediffusers/63) でDiffusersコミュニティに参加してユーザーや開発者と繋がって協力していきましょう。
|
| 22 |
+
|
| 23 |
+
さあ、「拡散」をはじめていきましょう!🧨
|
tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/_toctree.yml
ADDED
|
@@ -0,0 +1,200 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
- sections:
|
| 2 |
+
- local: index
|
| 3 |
+
title: 🧨 Diffusers
|
| 4 |
+
- local: quicktour
|
| 5 |
+
title: "훑어보기"
|
| 6 |
+
- local: stable_diffusion
|
| 7 |
+
title: Stable Diffusion
|
| 8 |
+
- local: installation
|
| 9 |
+
title: 설치
|
| 10 |
+
title: 시작하기
|
| 11 |
+
- sections:
|
| 12 |
+
- local: tutorials/tutorial_overview
|
| 13 |
+
title: 개요
|
| 14 |
+
- local: using-diffusers/write_own_pipeline
|
| 15 |
+
title: 모델과 스케줄러 이해하기
|
| 16 |
+
- local: in_translation # tutorials/autopipeline
|
| 17 |
+
title: (번역중) AutoPipeline
|
| 18 |
+
- local: tutorials/basic_training
|
| 19 |
+
title: Diffusion 모델 학습하기
|
| 20 |
+
- local: in_translation # tutorials/using_peft_for_inference
|
| 21 |
+
title: (번역중) 추론을 위한 LoRAs 불러오기
|
| 22 |
+
- local: in_translation # tutorials/fast_diffusion
|
| 23 |
+
title: (번역중) Text-to-image diffusion 모델 추론 가속화하기
|
| 24 |
+
- local: in_translation # tutorials/inference_with_big_models
|
| 25 |
+
title: (번역중) 큰 모델로 작업하기
|
| 26 |
+
title: 튜토리얼
|
| 27 |
+
- sections:
|
| 28 |
+
- local: using-diffusers/loading
|
| 29 |
+
title: 파이프라인 불러오기
|
| 30 |
+
- local: using-diffusers/custom_pipeline_overview
|
| 31 |
+
title: 커뮤니티 파이프라인과 컴포넌트 불러오기
|
| 32 |
+
- local: using-diffusers/schedulers
|
| 33 |
+
title: 스케줄러와 모델 불러오기
|
| 34 |
+
- local: using-diffusers/other-formats
|
| 35 |
+
title: 모델 파일과 레이아웃
|
| 36 |
+
- local: using-diffusers/loading_adapters
|
| 37 |
+
title: 어댑터 불러오기
|
| 38 |
+
- local: using-diffusers/push_to_hub
|
| 39 |
+
title: 파일들을 Hub로 푸시하기
|
| 40 |
+
title: 파이프라인과 어댑터 불러오기
|
| 41 |
+
- sections:
|
| 42 |
+
- local: using-diffusers/unconditional_image_generation
|
| 43 |
+
title: Unconditional 이미지 생성
|
| 44 |
+
- local: using-diffusers/conditional_image_generation
|
| 45 |
+
title: Text-to-image
|
| 46 |
+
- local: using-diffusers/img2img
|
| 47 |
+
title: Image-to-image
|
| 48 |
+
- local: using-diffusers/inpaint
|
| 49 |
+
title: 인페인팅
|
| 50 |
+
- local: in_translation # using-diffusers/text-img2vid
|
| 51 |
+
title: (번역중) Text 또는 image-to-video
|
| 52 |
+
- local: using-diffusers/depth2img
|
| 53 |
+
title: Depth-to-image
|
| 54 |
+
title: 생성 태스크
|
| 55 |
+
- sections:
|
| 56 |
+
- local: in_translation # using-diffusers/overview_techniques
|
| 57 |
+
title: (번역중) 개요
|
| 58 |
+
- local: training/distributed_inference
|
| 59 |
+
title: 여러 GPU를 사용한 분산 추론
|
| 60 |
+
- local: in_translation # using-diffusers/merge_loras
|
| 61 |
+
title: (번역중) LoRA 병합
|
| 62 |
+
- local: in_translation # using-diffusers/scheduler_features
|
| 63 |
+
title: (번역중) 스케줄러 기능
|
| 64 |
+
- local: in_translation # using-diffusers/callback
|
| 65 |
+
title: (번역중) 파이프라인 콜백
|
| 66 |
+
- local: in_translation # using-diffusers/reusing_seeds
|
| 67 |
+
title: (번역중) 재현 가능한 파이프라인
|
| 68 |
+
- local: in_translation # using-diffusers/image_quality
|
| 69 |
+
title: (번역중) 이미지 퀄리티 조절하기
|
| 70 |
+
- local: using-diffusers/weighted_prompts
|
| 71 |
+
title: 프롬프트 기술
|
| 72 |
+
title: 추론 테크닉
|
| 73 |
+
- sections:
|
| 74 |
+
- local: in_translation # advanced_inference/outpaint
|
| 75 |
+
title: (번역중) Outpainting
|
| 76 |
+
title: 추론 심화
|
| 77 |
+
- sections:
|
| 78 |
+
- local: in_translation # using-diffusers/sdxl
|
| 79 |
+
title: (번역중) Stable Diffusion XL
|
| 80 |
+
- local: using-diffusers/sdxl_turbo
|
| 81 |
+
title: SDXL Turbo
|
| 82 |
+
- local: using-diffusers/kandinsky
|
| 83 |
+
title: Kandinsky
|
| 84 |
+
- local: in_translation # using-diffusers/ip_adapter
|
| 85 |
+
title: (번역중) IP-Adapter
|
| 86 |
+
- local: in_translation # using-diffusers/pag
|
| 87 |
+
title: (번역중) PAG
|
| 88 |
+
- local: in_translation # using-diffusers/controlnet
|
| 89 |
+
title: (번역중) ControlNet
|
| 90 |
+
- local: in_translation # using-diffusers/t2i_adapter
|
| 91 |
+
title: (번역중) T2I-Adapter
|
| 92 |
+
- local: in_translation # using-diffusers/inference_with_lcm
|
| 93 |
+
title: (번역중) Latent Consistency Model
|
| 94 |
+
- local: using-diffusers/textual_inversion_inference
|
| 95 |
+
title: Textual inversion
|
| 96 |
+
- local: using-diffusers/shap-e
|
| 97 |
+
title: Shap-E
|
| 98 |
+
- local: using-diffusers/diffedit
|
| 99 |
+
title: DiffEdit
|
| 100 |
+
- local: in_translation # using-diffusers/inference_with_tcd_lora
|
| 101 |
+
title: (번역중) Trajectory Consistency Distillation-LoRA
|
| 102 |
+
- local: using-diffusers/svd
|
| 103 |
+
title: Stable Video Diffusion
|
| 104 |
+
- local: in_translation # using-diffusers/marigold_usage
|
| 105 |
+
title: (번역중) Marigold 컴퓨터 비전
|
| 106 |
+
title: 특정 파이프라인 예시
|
| 107 |
+
- sections:
|
| 108 |
+
- local: training/overview
|
| 109 |
+
title: 개요
|
| 110 |
+
- local: training/create_dataset
|
| 111 |
+
title: 학습을 위한 데이터셋 생성하기
|
| 112 |
+
- local: training/adapt_a_model
|
| 113 |
+
title: 새로운 태스크에 모델 적용하기
|
| 114 |
+
- isExpanded: false
|
| 115 |
+
sections:
|
| 116 |
+
- local: training/unconditional_training
|
| 117 |
+
title: Unconditional 이미지 생성
|
| 118 |
+
- local: training/text2image
|
| 119 |
+
title: Text-to-image
|
| 120 |
+
- local: in_translation # training/sdxl
|
| 121 |
+
title: (번역중) Stable Diffusion XL
|
| 122 |
+
- local: in_translation # training/kandinsky
|
| 123 |
+
title: (번역중) Kandinsky 2.2
|
| 124 |
+
- local: in_translation # training/wuerstchen
|
| 125 |
+
title: (번역중) Wuerstchen
|
| 126 |
+
- local: training/controlnet
|
| 127 |
+
title: ControlNet
|
| 128 |
+
- local: in_translation # training/t2i_adapters
|
| 129 |
+
title: (번역중) T2I-Adapters
|
| 130 |
+
- local: training/instructpix2pix
|
| 131 |
+
title: InstructPix2Pix
|
| 132 |
+
title: 모델
|
| 133 |
+
- isExpanded: false
|
| 134 |
+
sections:
|
| 135 |
+
- local: training/text_inversion
|
| 136 |
+
title: Textual Inversion
|
| 137 |
+
- local: training/dreambooth
|
| 138 |
+
title: DreamBooth
|
| 139 |
+
- local: training/lora
|
| 140 |
+
title: LoRA
|
| 141 |
+
- local: training/custom_diffusion
|
| 142 |
+
title: Custom Diffusion
|
| 143 |
+
- local: in_translation # training/lcm_distill
|
| 144 |
+
title: (번역중) Latent Consistency Distillation
|
| 145 |
+
- local: in_translation # training/ddpo
|
| 146 |
+
title: (번역중) DDPO 강화학습 훈련
|
| 147 |
+
title: 메서드
|
| 148 |
+
title: 학습
|
| 149 |
+
- sections:
|
| 150 |
+
- local: optimization/fp16
|
| 151 |
+
title: 추론 스피드업
|
| 152 |
+
- local: in_translation # optimization/memory
|
| 153 |
+
title: (번역중) 메모리 사용량 줄이기
|
| 154 |
+
- local: optimization/torch2.0
|
| 155 |
+
title: PyTorch 2.0
|
| 156 |
+
- local: optimization/xformers
|
| 157 |
+
title: xFormers
|
| 158 |
+
- local: optimization/tome
|
| 159 |
+
title: Token merging
|
| 160 |
+
- local: in_translation # optimization/deepcache
|
| 161 |
+
title: (번역중) DeepCache
|
| 162 |
+
- local: in_translation # optimization/tgate
|
| 163 |
+
title: (번역중) TGATE
|
| 164 |
+
- sections:
|
| 165 |
+
- local: using-diffusers/stable_diffusion_jax_how_to
|
| 166 |
+
title: JAX/Flax
|
| 167 |
+
- local: optimization/onnx
|
| 168 |
+
title: ONNX
|
| 169 |
+
- local: optimization/open_vino
|
| 170 |
+
title: OpenVINO
|
| 171 |
+
- local: optimization/coreml
|
| 172 |
+
title: Core ML
|
| 173 |
+
title: 최적화된 모델 형식
|
| 174 |
+
- sections:
|
| 175 |
+
- local: optimization/mps
|
| 176 |
+
title: Metal Performance Shaders (MPS)
|
| 177 |
+
- local: optimization/habana
|
| 178 |
+
title: Intel Gaudi
|
| 179 |
+
title: 최적화된 하드웨어
|
| 180 |
+
title: 추론 가속화와 메모리 줄이기
|
| 181 |
+
- sections:
|
| 182 |
+
- local: conceptual/philosophy
|
| 183 |
+
title: 철학
|
| 184 |
+
- local: using-diffusers/controlling_generation
|
| 185 |
+
title: 제어된 생성
|
| 186 |
+
- local: conceptual/contribution
|
| 187 |
+
title: 어떻게 기여하나요?
|
| 188 |
+
- local: conceptual/ethical_guidelines
|
| 189 |
+
title: Diffusers의 윤리적 가이드라인
|
| 190 |
+
- local: conceptual/evaluation
|
| 191 |
+
title: Diffusion Models 평가하기
|
| 192 |
+
title: 개념 가이드
|
| 193 |
+
- sections:
|
| 194 |
+
- sections:
|
| 195 |
+
- sections:
|
| 196 |
+
- local: api/pipelines/stable_diffusion/stable_diffusion_xl
|
| 197 |
+
title: Stable Diffusion XL
|
| 198 |
+
title: Stable Diffusion
|
| 199 |
+
title: Pipelines
|
| 200 |
+
title: API
|
tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/api/pipelines/stable_diffusion/stable_diffusion_xl.md
ADDED
|
@@ -0,0 +1,400 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2024 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Stable diffusion XL
|
| 14 |
+
|
| 15 |
+
Stable Diffusion XL은 Dustin Podell, Zion English, Kyle Lacey, Andreas Blattmann, Tim Dockhorn, Jonas Müller, Joe Penna, Robin Rombach에 의해 [SDXL: Improving Latent Diffusion Models for High-Resolution Image Synthesis](https://huggingface.co/papers/2307.01952)에서 제안되었습니다.
|
| 16 |
+
|
| 17 |
+
논문 초록은 다음을 따릅니다:
|
| 18 |
+
|
| 19 |
+
*text-to-image의 latent diffusion 모델인 SDXL을 소개합니다. 이전 버전의 Stable Diffusion과 비교하면, SDXL은 세 배 더큰 규모의 UNet 백본을 포함합니다: 모델 파라미터의 증가는 많은 attention 블럭을 사용하고 더 큰 cross-attention context를 SDXL의 두 번째 텍스트 인코더에 사용하기 때문입니다. 다중 종횡비에 다수의 새로운 conditioning 방법을 구성했습니다. 또한 후에 수정하는 image-to-image 기술을 사용함으로써 SDXL에 의해 생성된 시각적 품질을 향상하기 위해 정제된 모델을 소개합니다. SDXL은 이전 버전의 Stable Diffusion보다 성능이 향상되었고, 이러한 black-box 최신 이미지 생성자와 경쟁력있는 결과를 달성했습니다.*
|
| 20 |
+
|
| 21 |
+
## 팁
|
| 22 |
+
|
| 23 |
+
- Stable Diffusion XL은 특히 786과 1024사이의 이미지에 잘 작동합니다.
|
| 24 |
+
- Stable Diffusion XL은 아래와 같이 학습된 각 텍스트 인코더에 대해 서로 다른 프롬프트를 전달할 수 있습니다. 동일한 프롬프트의 다른 부분을 텍스트 인코더에 전달할 수도 있습니다.
|
| 25 |
+
- Stable Diffusion XL 결과 이미지는 아래에 보여지듯이 정제기(refiner)를 사용함으로써 향상될 수 있습니다.
|
| 26 |
+
|
| 27 |
+
### 이용가능한 체크포인트:
|
| 28 |
+
|
| 29 |
+
- *Text-to-Image (1024x1024 해상도)*: [`StableDiffusionXLPipeline`]을 사용한 [stabilityai/stable-diffusion-xl-base-1.0](https://huggingface.co/stabilityai/stable-diffusion-xl-base-1.0)
|
| 30 |
+
- *Image-to-Image / 정제기(refiner) (1024x1024 해상도)*: [`StableDiffusionXLImg2ImgPipeline`]를 사용한 [stabilityai/stable-diffusion-xl-refiner-1.0](https://huggingface.co/stabilityai/stable-diffusion-xl-refiner-1.0)
|
| 31 |
+
|
| 32 |
+
## 사용 예시
|
| 33 |
+
|
| 34 |
+
SDXL을 사용하기 전에 `transformers`, `accelerate`, `safetensors` 와 `invisible_watermark`를 설치하세요.
|
| 35 |
+
다음과 같이 라이브러리를 설치할 수 있습니다:
|
| 36 |
+
|
| 37 |
+
```sh
|
| 38 |
+
pip install transformers
|
| 39 |
+
pip install accelerate
|
| 40 |
+
pip install safetensors
|
| 41 |
+
pip install invisible-watermark>=0.2.0
|
| 42 |
+
```
|
| 43 |
+
|
| 44 |
+
### 워터마커
|
| 45 |
+
|
| 46 |
+
Stable Diffusion XL로 이미지를 생성할 때 워터마크가 보이지 않도록 추가하는 것을 권장하는데, 이는 다운스트림(downstream) 어플리케이션에서 기계에 합성되었는지를 식별하는데 도움을 줄 수 있습니다. 그렇게 하려면 [invisible_watermark 라이브러리](https://pypi.org/project/invisible-watermark/)를 통해 설치해주세요:
|
| 47 |
+
|
| 48 |
+
|
| 49 |
+
```sh
|
| 50 |
+
pip install invisible-watermark>=0.2.0
|
| 51 |
+
```
|
| 52 |
+
|
| 53 |
+
`invisible-watermark` 라이브러리가 설치되면 워터마커가 **기본적으로** 사용될 것입니다.
|
| 54 |
+
|
| 55 |
+
생성 또는 안전하게 이미지를 배포하기 위해 다른 규정이 있다면, 다음과 같이 워터마커를 비활성화할 수 있습니다:
|
| 56 |
+
|
| 57 |
+
```py
|
| 58 |
+
pipe = StableDiffusionXLPipeline.from_pretrained(..., add_watermarker=False)
|
| 59 |
+
```
|
| 60 |
+
|
| 61 |
+
### Text-to-Image
|
| 62 |
+
|
| 63 |
+
*text-to-image*를 위해 다음과 같이 SDXL을 사용할 수 있습니다:
|
| 64 |
+
|
| 65 |
+
```py
|
| 66 |
+
from diffusers import StableDiffusionXLPipeline
|
| 67 |
+
import torch
|
| 68 |
+
|
| 69 |
+
pipe = StableDiffusionXLPipeline.from_pretrained(
|
| 70 |
+
"stabilityai/stable-diffusion-xl-base-1.0", torch_dtype=torch.float16, variant="fp16", use_safetensors=True
|
| 71 |
+
)
|
| 72 |
+
pipe.to("cuda")
|
| 73 |
+
|
| 74 |
+
prompt = "Astronaut in a jungle, cold color palette, muted colors, detailed, 8k"
|
| 75 |
+
image = pipe(prompt=prompt).images[0]
|
| 76 |
+
```
|
| 77 |
+
|
| 78 |
+
### Image-to-image
|
| 79 |
+
|
| 80 |
+
*image-to-image*를 위해 다음과 같이 SDXL을 사용할 수 있습니다:
|
| 81 |
+
|
| 82 |
+
```py
|
| 83 |
+
import torch
|
| 84 |
+
from diffusers import StableDiffusionXLImg2ImgPipeline
|
| 85 |
+
from diffusers.utils import load_image
|
| 86 |
+
|
| 87 |
+
pipe = StableDiffusionXLImg2ImgPipeline.from_pretrained(
|
| 88 |
+
"stabilityai/stable-diffusion-xl-refiner-1.0", torch_dtype=torch.float16, variant="fp16", use_safetensors=True
|
| 89 |
+
)
|
| 90 |
+
pipe = pipe.to("cuda")
|
| 91 |
+
url = "https://huggingface.co/datasets/patrickvonplaten/images/resolve/main/aa_xl/000000009.png"
|
| 92 |
+
|
| 93 |
+
init_image = load_image(url).convert("RGB")
|
| 94 |
+
prompt = "a photo of an astronaut riding a horse on mars"
|
| 95 |
+
image = pipe(prompt, image=init_image).images[0]
|
| 96 |
+
```
|
| 97 |
+
|
| 98 |
+
### 인페인팅
|
| 99 |
+
|
| 100 |
+
*inpainting*를 위해 다음과 같이 SDXL을 사용할 수 있습니다:
|
| 101 |
+
|
| 102 |
+
```py
|
| 103 |
+
import torch
|
| 104 |
+
from diffusers import StableDiffusionXLInpaintPipeline
|
| 105 |
+
from diffusers.utils import load_image
|
| 106 |
+
|
| 107 |
+
pipe = StableDiffusionXLInpaintPipeline.from_pretrained(
|
| 108 |
+
"stabilityai/stable-diffusion-xl-base-1.0", torch_dtype=torch.float16, variant="fp16", use_safetensors=True
|
| 109 |
+
)
|
| 110 |
+
pipe.to("cuda")
|
| 111 |
+
|
| 112 |
+
img_url = "https://raw.githubusercontent.com/CompVis/latent-diffusion/main/data/inpainting_examples/overture-creations-5sI6fQgYIuo.png"
|
| 113 |
+
mask_url = "https://raw.githubusercontent.com/CompVis/latent-diffusion/main/data/inpainting_examples/overture-creations-5sI6fQgYIuo_mask.png"
|
| 114 |
+
|
| 115 |
+
init_image = load_image(img_url).convert("RGB")
|
| 116 |
+
mask_image = load_image(mask_url).convert("RGB")
|
| 117 |
+
|
| 118 |
+
prompt = "A majestic tiger sitting on a bench"
|
| 119 |
+
image = pipe(prompt=prompt, image=init_image, mask_image=mask_image, num_inference_steps=50, strength=0.80).images[0]
|
| 120 |
+
```
|
| 121 |
+
|
| 122 |
+
### 이미지 결과물을 정제하기
|
| 123 |
+
|
| 124 |
+
[base 모델 체크포인트](https://huggingface.co/stabilityai/stable-diffusion-xl-base-1.0)에서, StableDiffusion-XL 또한 고주파 품질을 향상시키는 이미지를 생성하기 위해 낮은 노이즈 단계 이미지를 제거하는데 특화된 [refiner 체크포인트](https://huggingface.co/stabilityai/stable-diffusion-xl-refiner-1.0)를 포함하고 있습니다. 이 refiner 체크포인트는 이미지 품질을 향상시키기 위해 base 체크포인트를 실행한 후 "두 번째 단계" 파이프라인에 사용될 수 있습니다.
|
| 125 |
+
|
| 126 |
+
refiner를 사용할 때, 쉽게 사용할 수 있습니다
|
| 127 |
+
- 1.) base 모델과 refiner을 사용하는데, 이는 *Denoisers의 앙상블*을 위한 첫 번째 제안된 [eDiff-I](https://research.nvidia.com/labs/dir/eDiff-I/)를 사용하거나
|
| 128 |
+
- 2.) base 모델을 거친 후 [SDEdit](https://huggingface.co/papers/2108.01073) 방법으로 단순하게 refiner를 실행시킬 수 있습니다.
|
| 129 |
+
|
| 130 |
+
**참고**: SD-XL base와 refiner를 앙상블로 사용하는 아이디어는 커뮤니티 기여자들이 처음으로 제안했으며, 이는 다음과 같은 `diffusers`를 구현하는 데도 도움을 주셨습니다.
|
| 131 |
+
- [SytanSD](https://github.com/SytanSD)
|
| 132 |
+
- [bghira](https://github.com/bghira)
|
| 133 |
+
- [Birch-san](https://github.com/Birch-san)
|
| 134 |
+
- [AmericanPresidentJimmyCarter](https://github.com/AmericanPresidentJimmyCarter)
|
| 135 |
+
|
| 136 |
+
#### 1.) Denoisers의 앙상블
|
| 137 |
+
|
| 138 |
+
base와 refiner 모델을 denoiser의 앙상블로 사용할 때, base 모델은 고주파 diffusion 단계를 위한 전문가의 역할을 해야하고, refiner는 낮은 노이즈 diffusion 단계를 위한 전문가의 역할을 해야 합니다.
|
| 139 |
+
|
| 140 |
+
2.)에 비해 1.)의 장점은 전체적으로 denoising 단계가 덜 필요하므로 속도가 훨씬 더 빨라집니다. 단점은 base 모델의 결과를 검사할 수 없다는 것입니다. 즉, 여전히 노이즈가 심하게 제거됩니다.
|
| 141 |
+
|
| 142 |
+
base 모델과 refiner를 denoiser의 앙상블로 사용하기 위해 각각 고노이즈(high-nosise) (*즉* base 모델)와 저노이즈 (*즉* refiner 모델)의 노이즈를 제거하는 단계를 거쳐야하는 타임스텝의 기간을 정의해야 합니다.
|
| 143 |
+
base 모델의 [`denoising_end`](https://huggingface.co/docs/diffusers/main/en/api/pipelines/stable_diffusion/stable_diffusion_xl#diffusers.StableDiffusionXLPipeline.__call__.denoising_end)와 refiner 모델의 [`denoising_start`](https://huggingface.co/docs/diffusers/main/en/api/pipelines/stable_diffusion/stable_diffusion_xl#diffusers.StableDiffusionXLImg2ImgPipeline.__call__.denoising_start)를 사용해 간격을 정합니다.
|
| 144 |
+
|
| 145 |
+
`denoising_end`와 `denoising_start` 모두 0과 1사이의 실수 값으로 전달되어야 합니다.
|
| 146 |
+
전달되면 노이즈 제거의 끝과 시작은 모델 스케줄에 의해 정의된 이산적(discrete) 시간 간격의 비율로 정의됩니다.
|
| 147 |
+
노이즈 제거 단계의 수는 모델이 학습된 불연속적인 시간 간격과 선언된 fractional cutoff에 의해 결정되므로 '강도' 또한 선언된 경우 이 값이 '강도'를 재정의합니다.
|
| 148 |
+
|
| 149 |
+
예시를 들어보겠습니다.
|
| 150 |
+
우선, 두 개의 파이프라인을 가져옵니다. 텍스트 인코더와 variational autoencoder는 동일하므로 refiner를 위해 다시 불러오지 않아도 됩니다.
|
| 151 |
+
|
| 152 |
+
```py
|
| 153 |
+
from diffusers import DiffusionPipeline
|
| 154 |
+
import torch
|
| 155 |
+
|
| 156 |
+
base = DiffusionPipeline.from_pretrained(
|
| 157 |
+
"stabilityai/stable-diffusion-xl-base-1.0", torch_dtype=torch.float16, variant="fp16", use_safetensors=True
|
| 158 |
+
)
|
| 159 |
+
pipe.to("cuda")
|
| 160 |
+
|
| 161 |
+
refiner = DiffusionPipeline.from_pretrained(
|
| 162 |
+
"stabilityai/stable-diffusion-xl-refiner-1.0",
|
| 163 |
+
text_encoder_2=base.text_encoder_2,
|
| 164 |
+
vae=base.vae,
|
| 165 |
+
torch_dtype=torch.float16,
|
| 166 |
+
use_safetensors=True,
|
| 167 |
+
variant="fp16",
|
| 168 |
+
)
|
| 169 |
+
refiner.to("cuda")
|
| 170 |
+
```
|
| 171 |
+
|
| 172 |
+
이제 추론 단계의 수와 고노이즈에서 노이즈를 제거하는 단계(*즉* base 모델)를 거쳐 실행되는 지점을 정의합니다.
|
| 173 |
+
|
| 174 |
+
```py
|
| 175 |
+
n_steps = 40
|
| 176 |
+
high_noise_frac = 0.8
|
| 177 |
+
```
|
| 178 |
+
|
| 179 |
+
Stable Diffusion XL base 모델은 타임스텝 0-999에 학습되며 Stable Diffusion XL refiner는 포괄적인 낮은 노이즈 타임스텝인 0-199에 base 모델로 부터 파인튜닝되어, 첫 800 타임스텝 (높은 노이즈)에 base 모델을 사용하고 마지막 200 타입스텝 (낮은 노이즈)에서 refiner가 사용됩니다. 따라서, `high_noise_frac`는 0.8로 설정하고, 모든 200-999 스텝(노이즈 제거 타임스텝의 첫 80%)은 base 모델에 의해 수행되며 0-199 스텝(노이즈 제거 타임스텝의 마지막 20%)은 refiner 모델에 의해 수행됩니다.
|
| 180 |
+
|
| 181 |
+
기억하세요, 노이즈 제거 절차는 **높은 값**(높은 노이즈) 타임스텝에서 시작되고, **낮은 값** (낮은 노이즈) 타임스텝에서 끝납니다.
|
| 182 |
+
|
| 183 |
+
이제 두 파이프라인을 실행해봅시다. `denoising_end`과 `denoising_start`를 같은 값으로 설정하고 `num_inference_steps`는 상수로 유지합니다. 또한 base 모델의 출력은 잠재 공간에 있어야 한다는 점을 기억하세요:
|
| 184 |
+
|
| 185 |
+
```py
|
| 186 |
+
prompt = "A majestic lion jumping from a big stone at night"
|
| 187 |
+
|
| 188 |
+
image = base(
|
| 189 |
+
prompt=prompt,
|
| 190 |
+
num_inference_steps=n_steps,
|
| 191 |
+
denoising_end=high_noise_frac,
|
| 192 |
+
output_type="latent",
|
| 193 |
+
).images
|
| 194 |
+
image = refiner(
|
| 195 |
+
prompt=prompt,
|
| 196 |
+
num_inference_steps=n_steps,
|
| 197 |
+
denoising_start=high_noise_frac,
|
| 198 |
+
image=image,
|
| 199 |
+
).images[0]
|
| 200 |
+
```
|
| 201 |
+
|
| 202 |
+
이미지를 살펴보겠습니다.
|
| 203 |
+
|
| 204 |
+
| 원래의 이미지 | Denoiser들의 앙상블 |
|
| 205 |
+
|---|---|
|
| 206 |
+
|  | 
|
| 207 |
+
|
| 208 |
+
동일한 40 단계에서 base 모델을 실행한다면, 이미지의 디테일(예: 사자의 눈과 코)이 떨어졌을 것입니다:
|
| 209 |
+
|
| 210 |
+
<Tip>
|
| 211 |
+
|
| 212 |
+
앙상블 방식은 사용 가능한 모든 스케줄러에서 잘 작동합니다!
|
| 213 |
+
|
| 214 |
+
</Tip>
|
| 215 |
+
|
| 216 |
+
#### 2.) 노이즈가 완전히 제거된 기본 이미지에서 이미지 출력을 정제하기
|
| 217 |
+
|
| 218 |
+
일반적인 [`StableDiffusionImg2ImgPipeline`] 방식에서, 기본 모델에서 생성된 완전히 노이즈가 제거된 이미지는 [refiner checkpoint](https://huggingface.co/stabilityai/stable-diffusion-xl-refiner-1.0)를 사용해 더 향상시킬 수 있습니다.
|
| 219 |
+
|
| 220 |
+
이를 위해, 보통의 "base" text-to-image 파이프라인을 수행 후에 image-to-image 파이프라인으로써 refiner를 실행시킬 수 있습니다. base 모델의 출력을 잠재 공간에 남겨둘 수 있습니다.
|
| 221 |
+
|
| 222 |
+
```py
|
| 223 |
+
from diffusers import DiffusionPipeline
|
| 224 |
+
import torch
|
| 225 |
+
|
| 226 |
+
pipe = DiffusionPipeline.from_pretrained(
|
| 227 |
+
"stabilityai/stable-diffusion-xl-base-1.0", torch_dtype=torch.float16, variant="fp16", use_safetensors=True
|
| 228 |
+
)
|
| 229 |
+
pipe.to("cuda")
|
| 230 |
+
|
| 231 |
+
refiner = DiffusionPipeline.from_pretrained(
|
| 232 |
+
"stabilityai/stable-diffusion-xl-refiner-1.0",
|
| 233 |
+
text_encoder_2=pipe.text_encoder_2,
|
| 234 |
+
vae=pipe.vae,
|
| 235 |
+
torch_dtype=torch.float16,
|
| 236 |
+
use_safetensors=True,
|
| 237 |
+
variant="fp16",
|
| 238 |
+
)
|
| 239 |
+
refiner.to("cuda")
|
| 240 |
+
|
| 241 |
+
prompt = "Astronaut in a jungle, cold color palette, muted colors, detailed, 8k"
|
| 242 |
+
|
| 243 |
+
image = pipe(prompt=prompt, output_type="latent" if use_refiner else "pil").images[0]
|
| 244 |
+
image = refiner(prompt=prompt, image=image[None, :]).images[0]
|
| 245 |
+
```
|
| 246 |
+
|
| 247 |
+
| 원래의 이미지 | 정제된 이미지 |
|
| 248 |
+
|---|---|
|
| 249 |
+
|  |  |
|
| 250 |
+
|
| 251 |
+
<Tip>
|
| 252 |
+
|
| 253 |
+
refiner는 또한 인페인팅 설정에 잘 사용될 수 있습니다. 아래에 보여지듯이 [`StableDiffusionXLInpaintPipeline`] 클래스를 사용해서 만들어보세요.
|
| 254 |
+
|
| 255 |
+
</Tip>
|
| 256 |
+
|
| 257 |
+
Denoiser 앙상블 설정에서 인페인팅에 refiner를 사용하려면 다음을 수행하면 됩니다:
|
| 258 |
+
|
| 259 |
+
```py
|
| 260 |
+
from diffusers import StableDiffusionXLInpaintPipeline
|
| 261 |
+
from diffusers.utils import load_image
|
| 262 |
+
|
| 263 |
+
pipe = StableDiffusionXLInpaintPipeline.from_pretrained(
|
| 264 |
+
"stabilityai/stable-diffusion-xl-base-1.0", torch_dtype=torch.float16, variant="fp16", use_safetensors=True
|
| 265 |
+
)
|
| 266 |
+
pipe.to("cuda")
|
| 267 |
+
|
| 268 |
+
refiner = StableDiffusionXLInpaintPipeline.from_pretrained(
|
| 269 |
+
"stabilityai/stable-diffusion-xl-refiner-1.0",
|
| 270 |
+
text_encoder_2=pipe.text_encoder_2,
|
| 271 |
+
vae=pipe.vae,
|
| 272 |
+
torch_dtype=torch.float16,
|
| 273 |
+
use_safetensors=True,
|
| 274 |
+
variant="fp16",
|
| 275 |
+
)
|
| 276 |
+
refiner.to("cuda")
|
| 277 |
+
|
| 278 |
+
img_url = "https://raw.githubusercontent.com/CompVis/latent-diffusion/main/data/inpainting_examples/overture-creations-5sI6fQgYIuo.png"
|
| 279 |
+
mask_url = "https://raw.githubusercontent.com/CompVis/latent-diffusion/main/data/inpainting_examples/overture-creations-5sI6fQgYIuo_mask.png"
|
| 280 |
+
|
| 281 |
+
init_image = load_image(img_url).convert("RGB")
|
| 282 |
+
mask_image = load_image(mask_url).convert("RGB")
|
| 283 |
+
|
| 284 |
+
prompt = "A majestic tiger sitting on a bench"
|
| 285 |
+
num_inference_steps = 75
|
| 286 |
+
high_noise_frac = 0.7
|
| 287 |
+
|
| 288 |
+
image = pipe(
|
| 289 |
+
prompt=prompt,
|
| 290 |
+
image=init_image,
|
| 291 |
+
mask_image=mask_image,
|
| 292 |
+
num_inference_steps=num_inference_steps,
|
| 293 |
+
denoising_start=high_noise_frac,
|
| 294 |
+
output_type="latent",
|
| 295 |
+
).images
|
| 296 |
+
image = refiner(
|
| 297 |
+
prompt=prompt,
|
| 298 |
+
image=image,
|
| 299 |
+
mask_image=mask_image,
|
| 300 |
+
num_inference_steps=num_inference_steps,
|
| 301 |
+
denoising_start=high_noise_frac,
|
| 302 |
+
).images[0]
|
| 303 |
+
```
|
| 304 |
+
|
| 305 |
+
일반적인 SDE 설정에서 인페인팅에 refiner를 사용하기 위해, `denoising_end`와 `denoising_start`를 제거하고 refiner의 추론 단계의 수를 적게 선택하세요.
|
| 306 |
+
|
| 307 |
+
### 단독 체크포인트 파일 / 원래의 파일 형식으로 불러오기
|
| 308 |
+
|
| 309 |
+
[`~diffusers.loaders.FromSingleFileMixin.from_single_file`]를 사용함으로써 원래의 파일 형식을 `diffusers` 형식으로 불러올 수 있습니다:
|
| 310 |
+
|
| 311 |
+
```py
|
| 312 |
+
from diffusers import StableDiffusionXLPipeline, StableDiffusionXLImg2ImgPipeline
|
| 313 |
+
import torch
|
| 314 |
+
|
| 315 |
+
pipe = StableDiffusionXLPipeline.from_single_file(
|
| 316 |
+
"./sd_xl_base_1.0.safetensors", torch_dtype=torch.float16
|
| 317 |
+
)
|
| 318 |
+
pipe.to("cuda")
|
| 319 |
+
|
| 320 |
+
refiner = StableDiffusionXLImg2ImgPipeline.from_single_file(
|
| 321 |
+
"./sd_xl_refiner_1.0.safetensors", torch_dtype=torch.float16
|
| 322 |
+
)
|
| 323 |
+
refiner.to("cuda")
|
| 324 |
+
```
|
| 325 |
+
|
| 326 |
+
### 모델 offloading을 통해 메모리 최적화하기
|
| 327 |
+
|
| 328 |
+
out-of-memory 에러가 난다면, [`StableDiffusionXLPipeline.enable_model_cpu_offload`]을 사용하는 것을 권장합니다.
|
| 329 |
+
|
| 330 |
+
```diff
|
| 331 |
+
- pipe.to("cuda")
|
| 332 |
+
+ pipe.enable_model_cpu_offload()
|
| 333 |
+
```
|
| 334 |
+
|
| 335 |
+
그리고
|
| 336 |
+
|
| 337 |
+
```diff
|
| 338 |
+
- refiner.to("cuda")
|
| 339 |
+
+ refiner.enable_model_cpu_offload()
|
| 340 |
+
```
|
| 341 |
+
|
| 342 |
+
### `torch.compile`로 추론 속도를 올리기
|
| 343 |
+
|
| 344 |
+
`torch.compile`를 사용함으로써 추론 속도를 올릴 수 있습니다. 이는 **ca.** 20% 속도 향상이 됩니다.
|
| 345 |
+
|
| 346 |
+
```diff
|
| 347 |
+
+ pipe.unet = torch.compile(pipe.unet, mode="reduce-overhead", fullgraph=True)
|
| 348 |
+
+ refiner.unet = torch.compile(refiner.unet, mode="reduce-overhead", fullgraph=True)
|
| 349 |
+
```
|
| 350 |
+
|
| 351 |
+
### `torch < 2.0`일 때 실행하기
|
| 352 |
+
|
| 353 |
+
**참고** Stable Diffusion XL을 `torch`가 2.0 버전 미만에서 실행시키고 싶을 때, xformers 어텐션을 사용해주세요:
|
| 354 |
+
|
| 355 |
+
```sh
|
| 356 |
+
pip install xformers
|
| 357 |
+
```
|
| 358 |
+
|
| 359 |
+
```diff
|
| 360 |
+
+pipe.enable_xformers_memory_efficient_attention()
|
| 361 |
+
+refiner.enable_xformers_memory_efficient_attention()
|
| 362 |
+
```
|
| 363 |
+
|
| 364 |
+
## StableDiffusionXLPipeline
|
| 365 |
+
|
| 366 |
+
[[autodoc]] StableDiffusionXLPipeline
|
| 367 |
+
- all
|
| 368 |
+
- __call__
|
| 369 |
+
|
| 370 |
+
## StableDiffusionXLImg2ImgPipeline
|
| 371 |
+
|
| 372 |
+
[[autodoc]] StableDiffusionXLImg2ImgPipeline
|
| 373 |
+
- all
|
| 374 |
+
- __call__
|
| 375 |
+
|
| 376 |
+
## StableDiffusionXLInpaintPipeline
|
| 377 |
+
|
| 378 |
+
[[autodoc]] StableDiffusionXLInpaintPipeline
|
| 379 |
+
- all
|
| 380 |
+
- __call__
|
| 381 |
+
|
| 382 |
+
### 각 텍스트 인코더에 다른 프롬프트를 전달하기
|
| 383 |
+
|
| 384 |
+
Stable Diffusion XL는 두 개의 텍스트 인코더에 학습되었습니다. 기본 동작은 각 프롬프트에 동일한 프롬프트를 전달하는 것입니다. 그러나 [일부 사용자](https://github.com/huggingface/diffusers/issues/4004#issuecomment-1627764201)가 품질을 향상시킬 수 있다고 지적한 것처럼 텍스트 인코더마다 다른 프롬프트를 전달할 수 있습니다. 그렇게 하려면, `prompt_2`와 `negative_prompt_2`를 `prompt`와 `negative_prompt`에 전달해야 합니다. 그렇게 함으로써, 원래의 프롬프트들(`prompt`)과 부정 프롬프트들(`negative_prompt`)를 `텍스트 인코더`에 전달할 것입니다.(공식 SDXL 0.9/1.0의 [OpenAI CLIP-ViT/L-14](https://huggingface.co/openai/clip-vit-large-patch14)에서 볼 수 있습니다.) 그리고 `prompt_2`와 `negative_prompt_2`는 `text_encoder_2`에 전달됩니다.(공식 SDXL 0.9/1.0의 [OpenCLIP-ViT/bigG-14](https://huggingface.co/laion/CLIP-ViT-bigG-14-laion2B-39B-b160k)에서 볼 수 있습니다.)
|
| 385 |
+
|
| 386 |
+
```py
|
| 387 |
+
from diffusers import StableDiffusionXLPipeline
|
| 388 |
+
import torch
|
| 389 |
+
|
| 390 |
+
pipe = StableDiffusionXLPipeline.from_pretrained(
|
| 391 |
+
"stabilityai/stable-diffusion-xl-base-0.9", torch_dtype=torch.float16, variant="fp16", use_safetensors=True
|
| 392 |
+
)
|
| 393 |
+
pipe.to("cuda")
|
| 394 |
+
|
| 395 |
+
# OAI CLIP-ViT/L-14에 prompt가 전달됩니다
|
| 396 |
+
prompt = "Astronaut in a jungle, cold color palette, muted colors, detailed, 8k"
|
| 397 |
+
# OpenCLIP-ViT/bigG-14에 prompt_2가 전달됩니다
|
| 398 |
+
prompt_2 = "monet painting"
|
| 399 |
+
image = pipe(prompt=prompt, prompt_2=prompt_2).images[0]
|
| 400 |
+
```
|
tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/conceptual/contribution.md
ADDED
|
@@ -0,0 +1,511 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2024 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Diffusers에 기여하는 방법 🧨 [[how-to-contribute-to-diffusers-]]
|
| 14 |
+
|
| 15 |
+
오픈 소스 커뮤니티에서의 기여를 환영합니다! 누구나 참여할 수 있으며, 코드뿐만 아니라 질문에 답변하거나 문서를 개선하는 등 모든 유형의 참여가 가치 있고 감사히 여겨집니다. 질문에 답변하고 다른 사람들을 도와주며 소통하고 문서를 개선하는 것은 모두 커뮤니티에게 큰 도움이 됩니다. 따라서 관심이 있다면 두려워하지 말고 참여해보세요!
|
| 16 |
+
|
| 17 |
+
누구나 우리의 공개 Discord 채널에서 👋 인사하며 시작할 수 있도록 장려합니다. 우리는 diffusion 모델의 최신 동향을 논의하고 질문을 하며 개인 프로젝트를 자랑하고 기여에 대해 서로 도와주거나 그냥 어울리기 위해 모이는 곳입니다☕. <a href="https://Discord.gg/G7tWnz98XR"><img alt="Join us on Discord" src="https://img.shields.io/discord/823813159592001537?color=5865F2&logo=discord&logoColor=white"></a>
|
| 18 |
+
|
| 19 |
+
어떤 방식으로든 기여하려는 경우, 우리는 개방적이고 환영하며 친근한 커뮤니티의 일부가 되기 위해 노력하고 있습니다. 우리의 [행동 강령](https://github.com/huggingface/diffusers/blob/main/CODE_OF_CONDUCT.md)을 읽고 상호 작용 중에 이를 존중하도록 주의해주시기 바랍니다. 또한 프로젝트를 안내하는 [윤리 지침](https://huggingface.co/docs/diffusers/conceptual/ethical_guidelines)에 익숙해지고 동일한 투명성과 책임성의 원칙을 준수해주시기를 부탁드립니다.
|
| 20 |
+
|
| 21 |
+
우리는 커뮤니티로부터의 피드백을 매우 중요하게 생각하므로, 라이브러리를 개선하는 데 도움이 될 가치 있는 피드백이 있다고 생각되면 망설이지 말고 의견을 제시해주세요 - 모든 메시지, 댓글, 이슈, Pull Request(PR)는 읽히고 고려됩니다.
|
| 22 |
+
|
| 23 |
+
## 개요 [[overview]]
|
| 24 |
+
|
| 25 |
+
이슈에 있는 질문에 답변하는 것에서부터 코어 라이브러리에 새로운 diffusion 모델을 추가하는 것까지 다양한 방법으로 기여를 할 수 있습니다.
|
| 26 |
+
|
| 27 |
+
이어지는 부분에서 우리는 다양한 방법의 기여에 대한 개요를 난이도에 따라 오름차순으로 정리하였습니다. 모든 기여는 커뮤니티에게 가치가 있습니다.
|
| 28 |
+
|
| 29 |
+
1. [Diffusers 토론 포럼](https://discuss.huggingface.co/c/discussion-related-to-httpsgithubcomhuggingfacediffusers)이나 [Discord](https://discord.gg/G7tWnz98XR)에서 질문에 대답하거나 질문을 할 수 있습니다.
|
| 30 |
+
2. [GitHub Issues 탭](https://github.com/huggingface/diffusers/issues/new/choose)에서 새로운 이슈를 열 수 있습니다.
|
| 31 |
+
3. [GitHub Issues 탭](https://github.com/huggingface/diffusers/issues)에서 이슈에 대답할 수 있습니다.
|
| 32 |
+
4. "Good first issue" 라벨이 지정된 간단한 이슈를 수정할 수 있습니다. [여기](https://github.com/huggingface/diffusers/issues?q=is%3Aopen+is%3Aissue+label%3A%22good+first+issue%22)를 참조하세요.
|
| 33 |
+
5. [문서](https://github.com/huggingface/diffusers/tree/main/docs/source)에 기여할 수 있습니다.
|
| 34 |
+
6. [Community Pipeline](https://github.com/huggingface/diffusers/issues?q=is%3Aopen+is%3Aissue+label%3Acommunity-examples)에 기여할 수 있습니다.
|
| 35 |
+
7. [예제](https://github.com/huggingface/diffusers/tree/main/examples)에 기여할 수 있습니다.
|
| 36 |
+
8. "Good second issue" 라벨이 지정된 어려운 이슈를 수정할 수 있습니다. [여기](https://github.com/huggingface/diffusers/issues?q=is%3Aopen+is%3Aissue+label%3A%22Good+second+issue%22)를 참조하세요.
|
| 37 |
+
9. 새로운 파이프라인, 모델 또는 스케줄러를 추가할 수 있습니다. ["새로운 파이프라인/모델"](https://github.com/huggingface/diffusers/issues?q=is%3Aopen+is%3Aissue+label%3A%22New+pipeline%2Fmodel%22) 및 ["새로운 스케줄러"](https://github.com/huggingface/diffusers/issues?q=is%3Aopen+is%3Aissue+label%3A%22New+scheduler%22) 이슈를 참조하세요. 이 기여에 대해서는 [디자인 철학](https://github.com/huggingface/diffusers/blob/main/PHILOSOPHY.md)을 확인해주세요.
|
| 38 |
+
|
| 39 |
+
앞서 말한 대로, **모든 기여는 커뮤니티에게 가치가 있습니다**. 이어지는 부분에서 각 기여에 대해 조금 더 자세히 설명하겠습니다.
|
| 40 |
+
|
| 41 |
+
4부터 9까지의 모든 기여에는 Pull Request을 열어야 합니다. [Pull Request 열기](#how-to-open-a-pr)에서 자세히 ���명되어 있습니다.
|
| 42 |
+
|
| 43 |
+
### 1. Diffusers 토론 포럼이나 Diffusers Discord에서 질문하고 답변하기 [[1-asking-and-answering-questions-on-the-diffusers-discussion-forum-or-on-the-diffusers-discord]]
|
| 44 |
+
|
| 45 |
+
Diffusers 라이브러리와 관련된 모든 질문이나 의견은 [토론 포럼](https://discuss.huggingface.co/c/discussion-related-to-httpsgithubcomhuggingfacediffusers/63)이나 [Discord](https://discord.gg/G7tWnz98XR)에서 할 수 있습니다. 이러한 질문과 의견에는 다음과 같은 내용이 포함됩니다(하지만 이에 국한되지는 않습니다):
|
| 46 |
+
- 지식을 공유하기 위해서 훈련 또는 추론 실험에 대한 결과 보고
|
| 47 |
+
- 개인 프로젝트 소개
|
| 48 |
+
- 비공식 훈련 예제에 대한 질문
|
| 49 |
+
- 프로젝트 제안
|
| 50 |
+
- 일반적인 피드백
|
| 51 |
+
- 논문 요약
|
| 52 |
+
- Diffusers 라이브러리를 기반으로 하는 개인 프로젝트에 대한 도움 요청
|
| 53 |
+
- 일반적인 질문
|
| 54 |
+
- Diffusion 모델에 대한 윤리적 질문
|
| 55 |
+
- ...
|
| 56 |
+
|
| 57 |
+
포럼이나 Discord에서 질문을 하면 커뮤니티가 지식을 공개적으로 공유하도록 장려되며, 향후 동일한 질문을 가진 초보자에게도 도움이 될 수 있습니다. 따라서 궁금한 질문은 언제든지 하시기 바랍니다.
|
| 58 |
+
또한, 이러한 질문에 답변하는 것은 커뮤니티에게 매우 큰 도움이 됩니다. 왜냐하면 이렇게 하면 모두가 학습할 수 있는 공개적인 지식을 문서화하기 때문입니다.
|
| 59 |
+
|
| 60 |
+
**주의**하십시오. 질문이나 답변에 투자하는 노력이 많을수록 공개적으로 문서화된 지식의 품질이 높아집니다. 마찬가지로, 잘 정의되고 잘 답변된 질문은 모두에게 접근 가능한 고품질 지식 데이터베이스를 만들어줍니다. 반면에 잘못된 질문이나 답변은 공개 지식 데이터베이스의 전반적인 품질을 낮출 수 있습니다.
|
| 61 |
+
간단히 말해서, 고품질의 질문이나 답변은 *명확하고 간결하며 관련성이 있으며 이해하기 쉽고 접근 가능하며 잘 형식화되어 있어야* 합니다. 자세한 내용은 [좋은 이슈 작성 방법](#how-to-write-a-good-issue) 섹션을 참조하십시오.
|
| 62 |
+
|
| 63 |
+
**채널에 대한 참고사항**:
|
| 64 |
+
[*포럼*](https://discuss.huggingface.co/c/discussion-related-to-httpsgithubcomhuggingfacediffusers/63)은 구글과 같은 검색 엔진에서 더 잘 색인화됩니다. 게시물은 인기에 따라 순위가 매겨지며, 시간순으로 정렬되지 않습니다. 따라서 이전에 게시한 질문과 답변을 쉽게 찾을 수 있습니다.
|
| 65 |
+
또한, 포럼에 게시된 질문과 답변은 쉽게 링크할 수 있습니다.
|
| 66 |
+
반면 *Discord*는 채팅 형식으로 되어 있어 빠른 대화를 유도합니다.
|
| 67 |
+
질문에 대한 답변을 빠르게 받을 수는 있겠지만, 시간이 지나면 질문이 더 이상 보이지 않습니다. 또한, Discord에서 이전에 게시된 정보를 찾는 것은 훨씬 어렵습니다. 따라서 포럼을 사용하여 고품질의 질문과 답변을 하여 커뮤니티를 위한 오래 지속되는 지식을 만들기를 권장합니다. Discord에서의 토론이 매우 흥미로운 답변과 결론을 이끌어내는 경우, 해당 정보를 포럼에 게시하여 향후 독자들에게 더 쉽게 액세스할 수 있도록 권장합니다.
|
| 68 |
+
|
| 69 |
+
### 2. GitHub 이슈 탭에서 새로운 이슈 열기 [[2-opening-new-issues-on-the-github-issues-tab]]
|
| 70 |
+
|
| 71 |
+
🧨 Diffusers 라이브러리는 사용자들이 마주치는 문제를 알려주는 덕분에 견고하고 신뢰할 수 있습니다. 따라서 이슈를 보고해주셔서 감사합니다.
|
| 72 |
+
|
| 73 |
+
기억해주세요, GitHub 이슈는 Diffusers 라이브러리와 직접적으로 관련된 기술적인 질문, 버그 리포트, 기능 요청 또는 라이브러리 디자인에 대한 피드백에 사용됩니다.
|
| 74 |
+
|
| 75 |
+
간단히 말해서, Diffusers 라이브러리의 **코드와 관련되지 않은** 모든 것(문서 포함)은 GitHub가 아닌 [포럼](https://discuss.huggingface.co/c/discussion-related-to-httpsgithubcomhuggingfacediffusers/63)이나 [Discord](https://discord.gg/G7tWnz98XR)에서 질문해야 합니다.
|
| 76 |
+
|
| 77 |
+
**새로운 이슈를 열 때 다음 가이드라인을 고려해주세요**:
|
| 78 |
+
- 이미 같은 이슈가 있는지 검색했는지 확인해주세요(GitHub의 이슈 탭에서 검색 기능을 사용하세요).
|
| 79 |
+
- 다른(관련된) 이슈에 새로운 이슈를 보고하지 말아주세요. 다른 이슈와 관련이 높다면, 새로운 이슈를 열고 관련 이슈에 링크를 걸어주세요.
|
| 80 |
+
- 이슈를 영어로 작성해주세요. 영어에 익숙하지 않다면, [DeepL](https://www.deepl.com/translator)과 같은 뛰어난 무료 온라인 번역 서비스를 사용하여 모국어에서 영어로 번역해주세요.
|
| 81 |
+
- 이슈가 최신 Diffusers 버전으로 업데이트하면 해결될 수 있는지 확인해주세요. 이슈를 게시하기 전에 `python -c "import diffusers; print(diffusers.__version__)"` 명령을 실행하여 현재 사용 중인 Diffusers 버전이 최신 버전과 일��하거나 더 높은지 확인해주세요.
|
| 82 |
+
- 새로운 이슈를 열 때 투자하는 노력이 많을수록 답변의 품질이 높아지고 Diffusers 이슈 전체의 품질도 향상됩니다.
|
| 83 |
+
|
| 84 |
+
#### 2.1 재현 가능한 최소한의 버그 리포트 [[21-reproducible-minimal-bug-reports]]
|
| 85 |
+
|
| 86 |
+
|
| 87 |
+
버그 리포트는 항상 재현 가능한 코드 조각을 포함하고 가능한 한 최소한이어야 하며 간결해야 합니다.
|
| 88 |
+
자세히 말하면:
|
| 89 |
+
- 버그를 가능한 한 좁혀야 합니다. **전체 코드 파일을 그냥 던지지 마세요**.
|
| 90 |
+
- 코드의 서식을 지정해야 합니다.
|
| 91 |
+
- Diffusers가 의존하는 외부 라이브러리를 제외한 다른 외부 라이브러리는 포함하지 마십시오.
|
| 92 |
+
- **항상** 사용자 환경에 대한 모든 필요한 정보를 제공하세요. 이를 위해 쉘에서 `diffusers-cli env`를 실행하고 표시된 정보를 이슈에 복사하여 붙여넣을 수 있습니다.
|
| 93 |
+
- 이슈를 설명해야 합니다. 독자가 문제가 무엇인지, 왜 문제가 되는지 모른다면 이슈를 해결할 수 없습니다.
|
| 94 |
+
- **항상** 독자가 가능한 한 적은 노력으로 문제를 재현할 수 있어야 합니다. 코드 조각이 라이브러리가 없거나 정의되지 않은 변수 때문에 실행되지 않는 경우 독자가 도움을 줄 수 없습니다. 재현 가능한 코드 조각이 가능한 한 최소화되고 간단한 Python 셸에 복사하여 붙여넣을 수 있도록 해야 합니다.
|
| 95 |
+
- 문제를 재현하기 위해 모델과/또는 데이터셋이 필요한 경우 독자가 해당 모델이나 데이터셋에 접근할 수 있도록 해야 합니다. 모델이나 데이터셋을 [Hub](https://huggingface.co)에 업로드하여 쉽게 다운로드할 수 있도록 할 수 있습니다. 문제 재현을 가능한 한 쉽게하기 위해 모델과 데이터셋을 가능한 한 작게 유지하려고 노력하세요.
|
| 96 |
+
|
| 97 |
+
자세한 내용은 [좋은 이슈 작성 방법](#how-to-write-a-good-issue) 섹션을 참조하세요.
|
| 98 |
+
|
| 99 |
+
버그 리포트를 열려면 [여기](https://github.com/huggingface/diffusers/issues/new?assignees=&labels=bug&projects=&template=bug-report.yml)를 클릭하세요.
|
| 100 |
+
|
| 101 |
+
|
| 102 |
+
#### 2.2. 기능 요청 [[22-feature-requests]]
|
| 103 |
+
|
| 104 |
+
세계적인 기능 요청은 다음 사항을 다룹니다:
|
| 105 |
+
|
| 106 |
+
1. 먼저 동기부여:
|
| 107 |
+
* 라이브러리와 관련된 문제/불만이 있나요? 그렇다면 왜 그런지 설명해주세요. 문제를 보여주는 코드 조각을 제공하는 것이 가장 좋습니다.
|
| 108 |
+
* 프로젝트에 필요한 기능인가요? 우리는 그에 대해 듣고 싶습니다!
|
| 109 |
+
* 커뮤니티에 도움이 될 수 있는 것을 작업했고 그것에 대해 생각하고 있는가요? 멋지네요! 어떤 문제를 해결했는지 알려주세요.
|
| 110 |
+
2. 기능을 *상세히 설명하는* 문단을 작성해주세요;
|
| 111 |
+
3. 향후 사용을 보여주는 **코드 조각**을 제공해주세요;
|
| 112 |
+
4. 논문과 관련된 내용인 경우 링크를 첨부해주세요;
|
| 113 |
+
5. 도움이 될 수 있다고 생각되는 추가 정보(그림, 스크린샷 등)를 첨부해주세요.
|
| 114 |
+
|
| 115 |
+
기능 요청은 [여기](https://github.com/huggingface/diffusers/issues/new?assignees=&labels=&template=feature_request.md&title=)에서 열 수 있습니다.
|
| 116 |
+
|
| 117 |
+
#### 2.3 피드백 [[23-feedback]]
|
| 118 |
+
|
| 119 |
+
라이브러리 디자인과 그것이 왜 좋은지 또는 나쁜지에 대한 이유에 대한 피드백은 핵심 메인테이너가 사용자 친화적인 라이브러리를 만드는 데 엄청난 도움이 됩니다. 현재 디자인 철학을 이해하려면 [여기](https://huggingface.co/docs/diffusers/conceptual/philosophy)를 참조해 주세요. 특정 디자인 선택이 현재 디자인 철학과 맞지 않는다고 생각되면, 그 이유와 어떻게 변경되어야 하는지 설명해 주세요. 반대로 특정 디자인 선택이 디자인 철학을 너무 따르기 때문에 사용 사례를 제한한다고 생각되면, 그 이유와 어떻게 변경되어야 하는지 설명해 주세요. 특정 디자인 선택이 매우 유용하다고 생각되면, 향후 디자인 결정에 큰 도움이 되므로 이에 대한 의견을 남겨 주세요.
|
| 120 |
+
|
| 121 |
+
피드백에 관한 이슈는 [여기](https://github.com/huggingface/diffusers/issues/new?assignees=&labels=&template=feedback.md&title=)에서 열 수 있습니다.
|
| 122 |
+
|
| 123 |
+
#### 2.4 기술적인 질문 [[24-technical-questions]]
|
| 124 |
+
|
| 125 |
+
기술적인 질문은 주로 라이브러리의 특정 코드가 왜 특정 방식으로 작성되었는지 또는 코드의 특정 부분이 무엇을 하는지에 대한 질문입니다. 질문하신 코드 부분에 대한 링크를 제공하고 해당 코드 부분이 이해하기 어려운 이유에 대한 자세한 설명을 해주시기 바랍니다.
|
| 126 |
+
|
| 127 |
+
기술적인 질문에 관한 이슈를 [여기](https://github.com/huggingface/diffusers/issues/new?assignees=&labels=bug&template=bug-report.yml)에서 열 수 있습니다.
|
| 128 |
+
|
| 129 |
+
#### 2.5 새로운 모델, 스케줄러 또는 파이프라인 추가 제안 [[25-proposal-to-add-a-new-model-scheduler-or-pipeline]]
|
| 130 |
+
|
| 131 |
+
만약 diffusion 모델 커뮤니티에서 Diffusers 라이브러리에 추가하고 싶은 새로운 모델, 파이프라인 또는 스케줄러가 있다면, 다음 정보를 제공해주세요:
|
| 132 |
+
|
| 133 |
+
* Diffusion 파이프라인, 모델 또는 스케줄러에 대한 간단한 설명과 논문 또는 공개된 버전의 링크
|
| 134 |
+
* 해당 모델의 오픈 소스 구현에 대한 링크
|
| 135 |
+
* 모델 가중치가 있는 경우, 가중치의 링크
|
| 136 |
+
|
| 137 |
+
직접 모델에 기여하고 싶다면, 가장 잘 안내해드릴 수 있습니다. 또한, 가능하다면 구성 요소(모델, 스케줄러, 파이프라인 등)의 원저자를 GitHub 핸들로 태그하는 것을 잊지 마세요.
|
| 138 |
+
|
| 139 |
+
모델/파이프라인/스케줄러에 대한 요청을 [여기](https://github.com/huggingface/diffusers/issues/new?assignees=&labels=New+model%2Fpipeline%2Fscheduler&template=new-model-addition.yml)에서 열 수 있습니다.
|
| 140 |
+
|
| 141 |
+
### 3. GitHub 이슈 탭에서 문제에 대한 답변하기 [[3-answering-issues-on-the-github-issues-tab]]
|
| 142 |
+
|
| 143 |
+
GitHub에서 이슈에 대한 답변을 하기 위해서는 Diffusers에 대한 기술적인 지식이 필요할 수 있지만, 정확한 답변이 아니더라도 모두가 시도해기를 권장합니다. 이슈에 대한 고품질 답변을 제공하기 위한 몇 가지 팁:
|
| 144 |
+
- 가능한 한 간결하고 최소한으로 유지합니다.
|
| 145 |
+
- 주제에 집중합니다. 이슈에 대한 답변은 해당 이슈에 관련된 내용에만 집중해야 합니다.
|
| 146 |
+
- 자신의 주장을 증명하거나 장려하는 코드, 논문 또는 기타 출처는 링크를 제공하세요.
|
| 147 |
+
- 코드로 답변합니다. 간단한 코드 조각이 이슈에 대한 답변이거나 이슈를 해결하는 방법을 보여준다면, 완전히 재현 가능한 코드 조각을 제공해주세요.
|
| 148 |
+
|
| 149 |
+
또한, 많은 이슈들은 단순히 주제와 무관하거나 다른 이슈의 중복이거나 관련이 없는 경우가 많습니다. 이러한 이슈들에 대한 답변을 제공하고, 이슈 작성자에게 더 정확한 정보를 제공하거나, 중복된 이슈에 대한 링크를 제공하거나, [포럼](https://discuss.huggingface.co/c/discussion-related-to-httpsgithubcomhuggingfacediffusers/63) 이나 [Discord](https://discord.gg/G7tWnz98XR)로 리디렉션하는 것은 메인테이너에게 큰 도움이 됩니다.
|
| 150 |
+
|
| 151 |
+
이슈가 올바른 버그 보고서이고 소스 코드에서 수정이 필요하다고 확인한 경우, 다음 섹션을 살펴보세요.
|
| 152 |
+
|
| 153 |
+
다음 모든 기여에 대해서는 PR을 열여야 합니다. [Pull Request 열기](#how-to-open-a-pr) 섹션에서 자세히 설명되어 있습니다.
|
| 154 |
+
|
| 155 |
+
### 4. "Good first issue" 고치기 [[4-fixing-a-good-first-issue]]
|
| 156 |
+
|
| 157 |
+
*Good first issues*는 [Good first issue](https://github.com/huggingface/diffusers/issues?q=is%3Aopen+is%3Aissue+label%3A%22good+first+issue%22) 라벨로 표시됩니다. 일반적으로, 이슈는 이미 잠재적인 해결책이 어떻게 보이는지 설명하고 있어서 수정하기 쉽습니다.
|
| 158 |
+
만약 이슈가 아직 닫히지 않았고 이 문제를 해결해보고 싶다면, "이 이슈를 해결해보고 싶습니다."라는 메시지를 남기면 됩니다. 일반적으로 세 가지 시나리오가 있습니다:
|
| 159 |
+
- a.) 이슈 설명에 이미 수정 사항을 제안하는 경우, 해결책이 이해되고 합리적으로 보인다면, PR 또는 드래프트 PR을 열어서 수정할 수 있습니다.
|
| 160 |
+
- b.) 이슈 설명에 수정 사항이 제안되어 있지 않은 경우, 제안한 수정 사항이 가능할지 물어볼 수 있고, Diffusers 팀의 누군가가 곧 답변해줄 것입니다. 만약 어떻게 수정할지 좋은 아이디어가 있다면, 직접 PR을 열어도 됩니다.
|
| 161 |
+
- c.) 이미 이 문제를 해결하기 위해 열린 PR이 있지만, 이슈가 아직 닫히지 않았습니다. PR이 더 이상 진행되지 않았다면, 새로운 PR을 열고 이전 PR에 링크를 걸면 됩니다. PR은 종종 원래 기여자가 갑자기 시간을 내지 못해 더 이상 진행하지 못하는 경우에 더 이상 진행되지 않게 됩니다. 이는 오픈 소스에서 자주 발생하는 일이며 매우 정상적인 상황입니다. 이 경우, 커뮤니티는 새로 시도하고 기존 PR의 지식을 활용해주면 매우 기쁠 것입니다. 이미 PR이 있고 활성화되어 있다면, 제안을 해주거나 PR을 검토하거나 PR에 기여할 수 있는지 물어보는 등 작성자를 도와줄 수 있습니다.
|
| 162 |
+
|
| 163 |
+
|
| 164 |
+
### 5. 문서에 기여하기 [[5-contribute-to-the-documentation]]
|
| 165 |
+
|
| 166 |
+
좋은 라이브러리는 항상 좋은 문서를 갖고 있습니다! 공식 문서는 라이브러리를 처음 사용하는 사용자들에게 첫 번째 접점 중 하나이며, 따라서 문서에 기여하는 것은 매우 가치 있는 기여입니다.
|
| 167 |
+
|
| 168 |
+
라이브러리에 기여하는 방법은 다양합니다:
|
| 169 |
+
|
| 170 |
+
- 맞춤법이나 문법 오류를 수정합니다.
|
| 171 |
+
- 공식 문서가 이상하게 표시되거나 링크가 깨진 경우, 올바르게 수정하는 데 시간을 내주시면 ���우 기쁠 것입니다.
|
| 172 |
+
- 문서의 입력 또는 출력 텐서의 모양이나 차원을 수정합니다.
|
| 173 |
+
- 이해하기 어렵거나 잘못된 문서를 명확하게 합니다.
|
| 174 |
+
- 오래된 코드 예제를 업데이트합니다.
|
| 175 |
+
- 문서를 다른 언어로 번역합니다.
|
| 176 |
+
|
| 177 |
+
[공식 Diffusers 문서 페이지](https://huggingface.co/docs/diffusers/index)에 표시된 모든 내용은 공식 문서의 일부이며, 해당 [문서 소스](https://github.com/huggingface/diffusers/tree/main/docs/source)에서 수정할 수 있습니다.
|
| 178 |
+
|
| 179 |
+
문서에 대한 변경 사항을 로컬에서 확인하는 방법은 [이 페이지](https://github.com/huggingface/diffusers/tree/main/docs)를 참조해주세요.
|
| 180 |
+
|
| 181 |
+
|
| 182 |
+
### 6. 커뮤니티 파이프라인에 기여하기 [[6-contribute-a-community-pipeline]]
|
| 183 |
+
|
| 184 |
+
> [!TIP]
|
| 185 |
+
> 커뮤니티 파이프라인에 대해 자세히 알아보려면 [커뮤니티 파이프라인](../using-diffusers/custom_pipeline_overview#community-pipelines) 가이드를 읽어보세요. 커뮤니티 파이프라인이 왜 필요한지 궁금하다면 GitHub 이슈 [#841](https://github.com/huggingface/diffusers/issues/841)를 확인해보세요 (기본적으로, 우리는 diffusion 모델이 추론에 사용될 수 있는 모든 방법을 유지할 수 없지만 커뮤니티가 이를 구축하는 것을 방해하고 싶지 않습니다).
|
| 186 |
+
|
| 187 |
+
커뮤니티 파이프라인에 기여하는 것은 창의성과 작업을 커뮤니티와 공유하는 좋은 방법입니다. [`DiffusionPipeline`]을 기반으로 빌드하여 `custom_pipeline` 매개변수를 설정함으로써 누구나 로드하고 사용할 수 있도록 할 수 있습니다. 이 섹션에서는 UNet이 단일 순방향 패스만 수행하고 스케줄러를 한 번 호출하는 간단한 파이프라인 (단계별 파이프라인)을 만드는 방법을 안내합니다.
|
| 188 |
+
|
| 189 |
+
1. 커뮤니티 파이프라인을 위한 one_step_unet.py 파일을 생성하세요. 이 파일은 사용자에 의해 설치되는 패키지를 포함할 수 있지만, [`DiffusionPipeline`]에서 모델 가중치와 스케줄러 구성을 로드하기 위해 하나의 파이프라인 클래스만 있어야 합니다. `__init__` 함수에 UNet과 스케줄러를 추가하세요.
|
| 190 |
+
|
| 191 |
+
또한 [`~DiffusionPipeline.save_pretrained`]를 사용하여 파이프라인과 그 구성 요소를 저장할 수 있도록 `register_modules` 함수를 추가해야 합니다.
|
| 192 |
+
|
| 193 |
+
```py
|
| 194 |
+
from diffusers import DiffusionPipeline
|
| 195 |
+
import torch
|
| 196 |
+
|
| 197 |
+
class UnetSchedulerOneForwardPipeline(DiffusionPipeline):
|
| 198 |
+
def __init__(self, unet, scheduler):
|
| 199 |
+
super().__init__()
|
| 200 |
+
|
| 201 |
+
self.register_modules(unet=unet, scheduler=scheduler)
|
| 202 |
+
```
|
| 203 |
+
|
| 204 |
+
1. forward 패스에서 (`__call__`로 정의하는 것을 추천합니다), 원하는 어떤 기능이든 추가할 수 있습니다. "one-step" 파이프라인의 경우, 무작위 이미지를 생성하고 `timestep=1`로 설정하여 UNet과 스케줄러를 한 번 호출합니다.
|
| 205 |
+
|
| 206 |
+
```py
|
| 207 |
+
from diffusers import DiffusionPipeline
|
| 208 |
+
import torch
|
| 209 |
+
|
| 210 |
+
class UnetSchedulerOneForwardPipeline(DiffusionPipeline):
|
| 211 |
+
def __init__(self, unet, scheduler):
|
| 212 |
+
super().__init__()
|
| 213 |
+
|
| 214 |
+
self.register_modules(unet=unet, scheduler=scheduler)
|
| 215 |
+
|
| 216 |
+
def __call__(self):
|
| 217 |
+
image = torch.randn(
|
| 218 |
+
(1, self.unet.config.in_channels, self.unet.config.sample_size, self.unet.config.sample_size),
|
| 219 |
+
)
|
| 220 |
+
timestep = 1
|
| 221 |
+
|
| 222 |
+
model_output = self.unet(image, timestep).sample
|
| 223 |
+
scheduler_output = self.scheduler.step(model_output, timestep, image).prev_sample
|
| 224 |
+
|
| 225 |
+
return scheduler_output
|
| 226 |
+
```
|
| 227 |
+
|
| 228 |
+
이제 UNet과 스케줄러를 전달하여 파이프라인을 실행하거나, 파이프라인 구조가 동일한 경우 사전 학습된 가중치를 로드할 수 있습니다.
|
| 229 |
+
|
| 230 |
+
```py
|
| 231 |
+
from diffusers import DDPMScheduler, UNet2DModel
|
| 232 |
+
|
| 233 |
+
scheduler = DDPMScheduler()
|
| 234 |
+
unet = UNet2DModel()
|
| 235 |
+
|
| 236 |
+
pipeline = UnetSchedulerOneForwardPipeline(unet=unet, scheduler=scheduler)
|
| 237 |
+
output = pipeline()
|
| 238 |
+
# load pretrained weights
|
| 239 |
+
pipeline = UnetSchedulerOneForwardPipeline.from_pretrained("google/ddpm-cifar10-32", use_safetensors=True)
|
| 240 |
+
output = pipeline()
|
| 241 |
+
```
|
| 242 |
+
|
| 243 |
+
파이프라인을 GitHub 커뮤니티 파이프라인 또는 Hub 커뮤니티 파이프라인으로 공유할 수 있습니다.
|
| 244 |
+
|
| 245 |
+
<hfoptions id="pipeline type">
|
| 246 |
+
<hfoption id="GitHub pipeline">
|
| 247 |
+
|
| 248 |
+
GitHub 파이프라인을 공유하려면 Diffusers [저장소](https://github.com/huggingface/diffusers)에서 Pull Request를 열고 one_step_unet.py 파일을 [examples/community](https://github.com/huggingface/diffusers/tree/main/examples/community) 하위 폴더에 추가하세요.
|
| 249 |
+
|
| 250 |
+
</hfoption>
|
| 251 |
+
<hfoption id="Hub pipeline">
|
| 252 |
+
|
| 253 |
+
Hub 파이프라인을 공유하려면, 허브에 모델 저장소를 생성하고 one_step_unet.py 파일을 업로드하세요.
|
| 254 |
+
|
| 255 |
+
</hfoption>
|
| 256 |
+
</hfoptions>
|
| 257 |
+
|
| 258 |
+
### 7. 훈련 예제에 기여하기 [[7-contribute-to-training-examples]]
|
| 259 |
+
|
| 260 |
+
Diffusers 예제는 [examples](https://github.com/huggingface/diffusers/tree/main/examples) 폴더��� 있는 훈련 스크립트의 모음입니다.
|
| 261 |
+
|
| 262 |
+
두 가지 유형의 훈련 예제를 지원합니다:
|
| 263 |
+
|
| 264 |
+
- 공식 훈련 예제
|
| 265 |
+
- 연구용 훈련 예제
|
| 266 |
+
|
| 267 |
+
연구용 훈련 예제는 [examples/research_projects](https://github.com/huggingface/diffusers/tree/main/examples/research_projects)에 위치하며, 공식 훈련 예제는 `research_projects` 및 `community` 폴더를 제외한 [examples](https://github.com/huggingface/diffusers/tree/main/examples)의 모든 폴더를 포함합니다.
|
| 268 |
+
공식 훈련 예제는 Diffusers의 핵심 메인테이너가 유지 관리하며, 연구용 훈련 예제는 커뮤니티가 유지 관리합니다.
|
| 269 |
+
이는 공식 파이프라인 vs 커뮤니티 파이프라인에 대한 [6. 커뮤니티 파이프라인 기여하기](#6-contribute-a-community-pipeline)에서 제시한 이유와 동일합니다: 핵심 메인테이너가 diffusion 모델의 모든 가능한 훈련 방법을 유지 관리하는 것은 현실적으로 불가능합니다.
|
| 270 |
+
Diffusers 핵심 메인테이너와 커뮤니티가 특정 훈련 패러다임을 너무 실험적이거나 충분히 대중적이지 않다고 판단한다면, 해당 훈련 코드는 `research_projects` 폴더에 넣고 작성자에 의해 관리되어야 합니다.
|
| 271 |
+
|
| 272 |
+
공식 훈련 및 연구 예제는 하나 이상의 훈련 스크립트, requirements.txt 파일 및 README.md 파일을 포함하는 디렉토리로 구성됩니다. 사용자가 훈련 예제를 사용하려면 리포지토리를 복제해야 합니다:
|
| 273 |
+
|
| 274 |
+
```bash
|
| 275 |
+
git clone https://github.com/huggingface/diffusers
|
| 276 |
+
```
|
| 277 |
+
|
| 278 |
+
그리고 훈련에 필요한 모든 추가적인 의존성도 설치해야 합니다:
|
| 279 |
+
|
| 280 |
+
```bash
|
| 281 |
+
pip install -r /examples/<your-example-folder>/requirements.txt
|
| 282 |
+
```
|
| 283 |
+
|
| 284 |
+
따라서 예제를 추가할 때, `requirements.txt` 파일은 훈련 예제에 필요한 모든 pip 종속성을 정의해야 합니다. 이렇게 설치된 모든 종속성을 사용하여 사용자가 예제의 훈련 스크립트를 실행할 수 있어야 합니다. 예를 들어, [DreamBooth `requirements.txt` 파일](https://github.com/huggingface/diffusers/blob/main/examples/dreambooth/requirements.txt)을 참조하세요.
|
| 285 |
+
|
| 286 |
+
Diffusers 라이브러리의 훈련 예제는 다음 철학을 따라야 합니다:
|
| 287 |
+
- 예제를 실행하는 데 필요한 모든 코드는 하나의 Python 파일에 있어야 합니다.
|
| 288 |
+
- 사용자는 명령 줄에서 `python <your-example>.py --args`와 같이 예제를 실행할 수 있어야 합니다.
|
| 289 |
+
- 예제는 간단하게 유지되어야 하며, Diffusers를 사용한 훈련 방법을 보여주는 **예시**로 사용되어야 합니다. 예제 스크립트의 목적은 최첨단 diffusion 모델을 만드는 것이 아니라, 너무 많은 사용자 정의 로직을 추가하지 않고 이미 알려진 훈련 방법을 재현하는 것입니다. 이 점의 부산물로서, 예제는 좋은 교육 자료로써의 역할을 하기 위해 노력합니다.
|
| 290 |
+
|
| 291 |
+
예제에 기여하기 위해서는, 이미 존재하는 예제인 [dreambooth](https://github.com/huggingface/diffusers/blob/main/examples/dreambooth/train_dreambooth.py)와 같은 예제를 참고하여 어떻게 보여야 하는지에 대한 아이디어를 얻는 것이 매우 권장됩니다.
|
| 292 |
+
Diffusers와 긴밀하게 통합되어 있기 때문에, 기여자들이 [Accelerate 라이브러리](https://github.com/huggingface/accelerate)를 사용하는 것을 강력히 권장합니다.
|
| 293 |
+
예제 스크립트가 작동하는 경우, 반드시 예제를 정확하게 사용하는 방법을 설명하는 포괄적인 `README.md`를 추가해야 합니다. 이 README에는 다음이 포함되어야 합니다:
|
| 294 |
+
- [여기](https://github.com/huggingface/diffusers/tree/main/examples/dreambooth#running-locally-with-pytorch)에 표시된 예제 스크립트를 실행하는 방법에 대한 예제 명령어.
|
| 295 |
+
- [여기](https://api.wandb.ai/report/patrickvonplaten/xm6cd5q5)에 표시된 훈련 결과 (로그, 모델 등)에 대한 링크로 사용자가 기대할 수 있는 내용을 보여줍니다.
|
| 296 |
+
- 비공식/연구용 훈련 예제를 추가하는 경우, **반드시** git 핸들을 포함하여 이 훈련 예제를 유지 관리할 것임을 명시하는 문장을 추가해야 합니다. [여기](https://github.com/huggingface/diffusers/tree/main/examples/research_projects/intel_opts#diffusers-examples-with-intel-optimizations)에 표시된 것과 같습니다.
|
| 297 |
+
|
| 298 |
+
만약 공식 훈련 예제에 기여하는 경우, [examples/test_examples.py](https://github.com/huggingface/diffusers/blob/main/examples/test_examples.py)에 테스트를 추가하는 것도 확인해주세요. 비공식 훈련 예제에는 이 작업이 필요하지 않습니다.
|
| 299 |
+
|
| 300 |
+
### 8. "Good second issue" 고치기 [[8-fixing-a-good-second-issue]]
|
| 301 |
+
|
| 302 |
+
"Good second issue"는 [Good second issue](https://github.com/huggingface/diffusers/issues?q=is%3Aopen+is%3Aissue+label%3A%22Good+second+issue%22) 라벨로 표시됩니다. Good second issue는 [Good first issues](https://github.com/huggingface/diffusers/issues?q=is%3Aopen+is%3Aissue+label%3A%22good+first+issue%22)보다 해결하기가 더 복잡합니다.
|
| 303 |
+
이슈 설명은 일반적으로 이슈를 해결하는 방법에 대해 덜 구체적이며, 관심 있는 기여자는 라이브러리에 대한 꽤 깊은 이해가 필요합니다.
|
| 304 |
+
Good second issue를 해결하고자 하는 경우, 해당 이슈를 해결하기 위해 PR을 열고 PR을 이슈에 링크하세요. 이미 해당 이슈에 대한 PR이 열려있지만 병합되지 않은 경우, 왜 병합되지 않았는지 이해하기 위해 살펴보고 개선된 PR을 열어보세요.
|
| 305 |
+
Good second issue는 일반적으로 Good first issue 이슈보다 병합하기가 더 어려우므로, 핵심 메인테이너에게 도움을 요청하는 것이 좋습니다. PR이 거의 완료된 경우, 핵심 메인테이너는 PR에 참여하여 커밋하고 병합을 진행할 수 있습니다.
|
| 306 |
+
|
| 307 |
+
### 9. 파이프라인, 모델, 스케줄러 추가하기 [[9-adding-pipelines-models-schedulers]]
|
| 308 |
+
|
| 309 |
+
파이프라인, 모델, 스케줄러는 Diffusers 라이브러리에서 가장 중요한 부분입니다.
|
| 310 |
+
이들은 최첨단 diffusion 기술에 쉽게 접근하도록 하며, 따라서 커뮤니티가 강력한 생성형 AI 애플리케이션을 만들 수 있도록 합니다.
|
| 311 |
+
|
| 312 |
+
새로운 모델, 파이프라인 또는 스케줄러를 추가함으로써, 사용자 인터페이스에 새로운 강력한 사용 사례를 활성화할 수 있으며, 이는 전체 생성형 AI 생태계에 매우 중요한 가치를 제공할 수 있습니다.
|
| 313 |
+
|
| 314 |
+
Diffusers에는 세 가지 구성 요소에 대한 여러 개발 요청이 있습니다. 특정 구성 요소를 아직 정확히 어떤 것을 추가하고 싶은지 모르는 경우, 다음 링크를 참조하세요:
|
| 315 |
+
- [모델 또는 파이프라인](https://github.com/huggingface/diffusers/issues?q=is%3Aopen+is%3Aissue+label%3A%22New+pipeline%2Fmodel%22)
|
| 316 |
+
- [스케줄러](https://github.com/huggingface/diffusers/issues?q=is%3Aopen+is%3Aissue+label%3A%22New+scheduler%22)
|
| 317 |
+
|
| 318 |
+
|
| 319 |
+
세 가지 구성 요소를 추가하기 전에, [철학 가이드](philosophy)를 읽어보는 것을 강력히 권장합니다. 세 가지 구성 요소 중 어느 것을 추가하든, 디자인 철학과 관련된 API 일관성을 유지하기 위해 우리의 디자인 철학과 크게 다른 구성 요소는 병합할 수 없습니다. 디자인 선택에 근본적으로 동의하지 않는 경우, [피드백 이슈](https://github.com/huggingface/diffusers/issues/new?assignees=&labels=&template=feedback.md&title=)를 열어 해당 디자인 패턴/선택이 라이브러리 전체에서 변경되어야 하는지, 디자인 철학을 업데이트해야 하는지에 대해 논의할 수 있습니다. 라이브러리 전체의 일관성은 우리에게 매우 중요합니다.
|
| 320 |
+
|
| 321 |
+
PR에 원본 코드베이스/논문 링크를 추가하고, 가능하면 PR에서 원래 작성자에게 직접 알림을 보내어 진행 상황을 따라갈 수 있도록 해주세요.
|
| 322 |
+
|
| 323 |
+
PR에서 막힌 경우나 도움이 필요한 경우, 첫 번째 리뷰나 도움을 요청하는 메시지를 남기는 것을 주저하지 마세요.
|
| 324 |
+
|
| 325 |
+
#### Copied from mechanism [[copied-from-mechanism]]
|
| 326 |
+
|
| 327 |
+
`# Copied from mechanism` 은 파이프라인, 모델 또는 스케줄러 코드를 추가할 때 이해해야 할 독특하고 중요한 기능입니다. 이것은 Diffusers 코드베이스 전반에서 볼 수 있으며, 이를 사용하는 이유는 코드베이스를 이해하고 유지 관리하기 쉽게 만들기 위해서입니다. `# Copied from mechanism` 으로 표시된 코드는 복사한 코드와 정확히 동일하도록 강제됩니다. 이렇게 하면 `make fix-copies`를 실행할 때마다 여러 파일에 걸쳐 변경 사항을 쉽게 업데이트하고 전파할 수 있습니다.
|
| 328 |
+
|
| 329 |
+
예를 들어, 아래 코드 예제에서 [`~diffusers.pipelines.stable_diffusion.StableDiffusionPipelineOutput`]은 원래 코드이며, `AltDiffusionPipelineOutput`은 `# Copied from mechanism`을 사용하여 복사합니다. 유일한 차이점은 클래스 접두사를 `Stable`에서 `Alt`로 변경한 것입니다.
|
| 330 |
+
|
| 331 |
+
```py
|
| 332 |
+
# Copied from diffusers.pipelines.stable_diffusion.pipeline_output.StableDiffusionPipelineOutput with Stable->Alt
|
| 333 |
+
class AltDiffusionPipelineOutput(BaseOutput):
|
| 334 |
+
"""
|
| 335 |
+
Output class for Alt Diffusion pipelines.
|
| 336 |
+
|
| 337 |
+
Args:
|
| 338 |
+
images (`List[PIL.Image.Image]` or `np.ndarray`)
|
| 339 |
+
List of denoised PIL images of length `batch_size` or NumPy array of shape `(batch_size, height, width,
|
| 340 |
+
num_channels)`.
|
| 341 |
+
nsfw_content_detected (`List[bool]`)
|
| 342 |
+
List indicating whether the corresponding generated image contains "not-safe-for-work" (nsfw) content or
|
| 343 |
+
`None` if safety checking could not be performed.
|
| 344 |
+
"""
|
| 345 |
+
```
|
| 346 |
+
|
| 347 |
+
더 자세히 알고 싶다면 [~Don't~ Repeat Yourself*](https://huggingface.co/blog/transformers-design-philosophy#4-machine-learning-models-are-static) 블로그 포스트의 이 섹션을 읽어보세요.
|
| 348 |
+
|
| 349 |
+
## 좋은 이슈 작성 방법 [[how-to-write-a-good-issue]]
|
| 350 |
+
|
| 351 |
+
**���슈를 잘 작성할수록 빠르게 해결될 가능성이 높아집니다.**
|
| 352 |
+
|
| 353 |
+
1. 이슈에 적절한 템플릿을 사용했는지 확인하세요. [새 이슈를 열 때](https://github.com/huggingface/diffusers/issues/new/choose) 올바른 템플릿을 선택해야 합니다. *버그 보고서*, *기능 요청*, *API 디자인에 대한 피드백*, *새로운 모델/파이프라인/스케줄러 추가*, *포럼*, 또는 빈 이슈 중에서 선택하세요. 이슈를 열 때 올바른 템플릿을 선택하는 것이 중요합니다.
|
| 354 |
+
2. **명확성**: 이슈에 적합한 제목을 지정하세요. 이슈 설명을 가능한 간단하게 작성하세요. 이슈를 이해하고 해결하는 데 걸리는 시간을 줄이기 위해 가능한 한 명확하게 작성하세요. 하나의 이슈에 대해 여러 문제를 포함하지 않도록 주의하세요. 여러 문제를 발견한 경우, 각각의 이슈를 개별적으로 열어주세요. 버그인 경우, 어떤 버그인지 가능한 한 정확하게 설명해야 합니다. "diffusers에서 오류"와 같이 간단히 작성하지 마세요.
|
| 355 |
+
3. **재현 가능성**: 재현 가능한 코드 조각이 없으면 해결할 수 없습니다. 버그를 발견한 경우, 유지 관리자는 그 버그를 재현할 수 있어야 합니다. 이슈에 재현 가능한 코드 조각을 포함해야 합니다. 코드 조각은 Python 인터프리터에 복사하여 붙여넣을 수 있는 형태여야 합니다. 코드 조각이 작동해야 합니다. 즉, 누락된 import나 이미지에 대한 링크가 없어야 합니다. 이슈에는 오류 메시지와 정확히 동일한 오류 메시지를 재현하기 위해 수정하지 않고 복사하여 붙여넣을 수 있는 코드 조각이 포함되어야 합니다. 이슈에 사용자의 로컬 모델 가중치나 로컬 데이터를 사용하는 경우, 독자가 액세스할 수 없는 경우 이슈를 해결할 수 없습니다. 데이터나 모델을 공유할 수 없는 경우, 더미 모델이나 더미 데이터를 만들어 사용해보세요.
|
| 356 |
+
4. **간결성**: 가능한 한 간결하게 유지하여 독자가 문제를 빠르게 이해할 수 있도록 도와주세요. 문제와 관련이 없는 코드나 정보는 모두 제거해주세요. 버그를 발견한 경우, 문제를 설명하는 가장 간단한 코드 예제를 만들어보세요. 버그를 발견한 후에는 작업 흐름 전체를 문제에 던지는 것이 아니라, 에러가 발생하는 훈련 코드의 어느 부분이 문제인지 먼저 이해하고 몇 줄로 재현해보세요. 전체 데이터셋 대신 더미 데이터를 사용해보세요.
|
| 357 |
+
5. 링크 추가하기. 특정한 이름, 메서드, 또는 모델을 참조하는 경우, 독자가 더 잘 이해할 수 있도록 링크를 제공해주세요. 특정 PR이나 이슈를 참조하는 경우, 해당 이슈에 링크를 걸어주세요. 독자가 무엇을 말하는지 알고 있다고 가정하지 마세요. 이슈에 링크를 추가할수록 좋습니다.
|
| 358 |
+
6. 포맷팅. 코드를 파이썬 코드 구문으로, 에러 메시지를 일반 코드 구문으로 형식화하여 이슈를 깔끔하게 작성하세요. 자세한 내용은 [GitHub 공식 포맷팅 문서](https://docs.github.com/en/get-started/writing-on-github/getting-started-with-writing-and-formatting-on-github/basic-writing-and-formatting-syntax)를 참조하세요.
|
| 359 |
+
7. 여러분의 이슈를 단순히 해결해야 할 티켓으로 생각하지 말고, 잘 작성된 백과사전 항목으로 생각해보세요. 추가된 모든 이슈는 공개적으로 이용 가능한 지식에 대한 기여입니다. 잘 작성된 이슈를 추가함으로써 메인테이너가 여러분의 이슈를 더 쉽게 해결할 수 있게 할 뿐만 아니라, 전체 커뮤니티가 라이브러리의 특정 측면을 더 잘 이해할 수 있도록 도움을 주게 됩니다.
|
| 360 |
+
|
| 361 |
+
## 좋은 PR 작성 방법 [[how-to-write-a-good-pr]]
|
| 362 |
+
|
| 363 |
+
1. 카멜레온이 되세요. 기존의 디자인 패턴과 구문을 이해하고, 여러분이 추가하는 코드가 기존 코드베이스와 자연스럽게 어우러지도록 해야 합니다. 기존 디자인 패턴이나 사용자 인터페이스와 크게 다른 Pull Request들은 병합되지 않습니다.
|
| 364 |
+
2. 레이저처럼 집중하세요. Pull Request는 하나의 문제, 오직 하나의 문제만 해결해야 합니다. "이왕 추가하는 김에 다른 문제도 고치자"는 함정에 빠지지 않도록 주의하세요. 여러 개의 관련 없는 문제를 해결하는 한 번에 해결하는 Pull Request들은 검토하기가 훨씬 더 어렵습니다.
|
| 365 |
+
3. 도움이 되는 경우, 추가한 내용이 어떻게 사용되는지 예제 코드 조각을 추가해보세요.
|
| 366 |
+
4. Pull Request의 제목은 기여 내용을 요약해야 합니다.
|
| 367 |
+
5. Pull Request가 이슈를 해결하는 경우, Pull Request의 설명에 이슈 번호를 언급하여 연결되도록 해주세요 (이슈를 참조하는 사람들이 작업 중임을 알 수 있도록).
|
| 368 |
+
6. 진행 중인 작업을 나타내려면 제목에 `[WIP]`를 접두사로 붙여주세요. 이는 중복 작업을 피하고, 병합 준비가 된 PR과 구분할 수 있도록 도움이 됩니다.
|
| 369 |
+
7. [좋은 이슈를 작성하는 방법](#how-to-write-a-good-issue)에 설명된 대로 텍스트를 구성하고 형식을 지정해보세요.
|
| 370 |
+
8. 기존 테스트가 통과하는지 확인하세요
|
| 371 |
+
9. 높은 커버리지를 가진 테스트를 추가하세요. 품질 테스트가 없으면 병합할 수 없습니다.
|
| 372 |
+
- 새로운 `@slow` 테스트를 추가하는 경우, 다음 명령을 사용하여 통과하는지 확인하세요.
|
| 373 |
+
`RUN_SLOW=1 python -m pytest tests/test_my_new_model.py`.
|
| 374 |
+
CircleCI는 느린 테스트를 실행하지 않지만, GitHub Actions는 매일 실행합니다!
|
| 375 |
+
10. 모든 공개 메서드는 마크다운과 잘 작동하는 정보성 docstring을 가져야 합니다. 예시로 [`pipeline_latent_diffusion.py`](https://github.com/huggingface/diffusers/blob/main/src/diffusers/pipelines/latent_diffusion/pipeline_latent_diffusion.py)를 참조하세요.
|
| 376 |
+
11. 리포지토리가 빠르게 성장하고 있기 때문에, 리포지토리에 큰 부담을 주는 파일이 추가되지 않도록 주의해야 합니다. 이미지, 비디오 및 기타 텍스트가 아닌 파일을 포함합니다. 이러한 파일을 배치하기 위해 hf.co 호스팅 `dataset`인 [`hf-internal-testing`](https://huggingface.co/hf-internal-testing) 또는 [huggingface/documentation-images](https://huggingface.co/datasets/huggingface/documentation-images)를 활용하는 것이 우선입니다.
|
| 377 |
+
외부 기여인 경우, 이미지를 PR에 추가하고 Hugging Face 구성원에게 이미지를 이 데이터셋으로 이동하도록 요청하세요.
|
| 378 |
+
|
| 379 |
+
## PR을 열기 위한 방법 [[how-to-open-a-pr]]
|
| 380 |
+
|
| 381 |
+
코드를 작성하기 전에, 이미 누군가가 같은 작업을 하고 있는지 확인하기 위해 기존의 PR이나 이슈를 검색하는 것이 좋습니다. 확실하지 않은 경우, 피드백을 받기 위해 이슈를 열어보는 것이 항상 좋은 아이디어입니다.
|
| 382 |
+
|
| 383 |
+
🧨 Diffusers에 기여하기 위해서는 기본적인 `git` 사용법을 알아야 합니다. `git`은 가장 쉬운 도구는 아니지만, 가장 훌륭한 매뉴얼을 가지고 있습니다. 셸에서 `git --help`을 입력하고 즐기세요. 책을 선호하는 경우, [Pro Git](https://git-scm.com/book/en/v2)은 매우 좋은 참고 자료입니다.
|
| 384 |
+
|
| 385 |
+
다음 단계를 따라 기여를 시작하세요 ([지원되는 Python 버전](https://github.com/huggingface/diffusers/blob/main/setup.py#L244)):
|
| 386 |
+
|
| 387 |
+
1. 저장소 페이지에서 'Fork' 버튼을 클릭하여 [저장소](https://github.com/huggingface/diffusers)를 포크합니다. 이렇게 하면 코드의 사본이 GitHub 사용자 계정에 생성됩니다.
|
| 388 |
+
|
| 389 |
+
2. 포크한 저장소를 로컬 디스크에 클론하고, 기본 저장소를 원격으로 추가하세요:
|
| 390 |
+
|
| 391 |
+
```bash
|
| 392 |
+
$ git clone git@github.com:<your GitHub handle>/diffusers.git
|
| 393 |
+
$ cd diffusers
|
| 394 |
+
$ git remote add upstream https://github.com/huggingface/diffusers.git
|
| 395 |
+
```
|
| 396 |
+
|
| 397 |
+
3. 개발 변경 사항을 보관할 새로운 브랜치를 생성하세요:
|
| 398 |
+
|
| 399 |
+
```bash
|
| 400 |
+
$ git checkout -b a-descriptive-name-for-my-changes
|
| 401 |
+
```
|
| 402 |
+
|
| 403 |
+
`main` 브랜치 위에서 **절대** 작업하지 마세요.
|
| 404 |
+
|
| 405 |
+
4. 가상 환경에서 다음 명령을 실행하여 개발 환경을 설정하세요:
|
| 406 |
+
|
| 407 |
+
```bash
|
| 408 |
+
$ pip install -e ".[dev]"
|
| 409 |
+
```
|
| 410 |
+
|
| 411 |
+
만약 저장소를 이미 클론한 경우, 가장 최신 변경 사항을 가져오기 위해 `git pull`을 실행해야 할 수도 있습니다.
|
| 412 |
+
|
| 413 |
+
5. 기능을 브랜치에서 개발하세요.
|
| 414 |
+
|
| 415 |
+
기능을 작업하는 동안 테스트 스위트가 통과되는지 확인해야 합니다. 다음과 같이 변경 사항에 영향을 받는 테스트를 실행해야 합니다:
|
| 416 |
+
|
| 417 |
+
```bash
|
| 418 |
+
$ pytest tests/<TEST_TO_RUN>.py
|
| 419 |
+
```
|
| 420 |
+
|
| 421 |
+
테스트를 실행하기 전에 테스트를 위해 필요한 의존성들을 설치하였는지 확인하세요. 다음의 커맨드를 통해서 확인할 수 있습니다:
|
| 422 |
+
|
| 423 |
+
```bash
|
| 424 |
+
$ pip install -e ".[test]"
|
| 425 |
+
```
|
| 426 |
+
|
| 427 |
+
다음 명령어로 전체 테스트 묶음 실행할 수도 있지만, Diffusers가 많이 성장하였기 때문에 결과를 적당한 시간 내에 생성하기 위해서는 강력한 컴퓨터가 필요합니다. 다음은 해당 명령어입니다:
|
| 428 |
+
|
| 429 |
+
```bash
|
| 430 |
+
$ make test
|
| 431 |
+
```
|
| 432 |
+
|
| 433 |
+
🧨 Diffusers는 소스 코드를 일관되게 포맷팅하기 위해 `black`과 `isort`를 사용합니다. 변경 사항을 적용한 후에는 다음과 같이 자동 스타일 수정 및 코드 검증을 적용할 수 있습니다:
|
| 434 |
+
|
| 435 |
+
|
| 436 |
+
```bash
|
| 437 |
+
$ make style
|
| 438 |
+
```
|
| 439 |
+
|
| 440 |
+
🧨 Diffusers `ruff`와 몇개의 커스텀 스크립트를 이용하여 코딩 실수를 확인합니다. 품질 제어는 CI에서 작동하지만, 동일한 검사를 다음을 통해서도 할 수 있습니다:
|
| 441 |
+
|
| 442 |
+
```bash
|
| 443 |
+
$ make quality
|
| 444 |
+
```
|
| 445 |
+
|
| 446 |
+
변경사항에 대해 만족한다면 `git add`를 사용하여 변경된 파일을 추가하고 `git commit`을 사용하여 변경사항에 대해 로컬상으로 저장한���:
|
| 447 |
+
|
| 448 |
+
```bash
|
| 449 |
+
$ git add modified_file.py
|
| 450 |
+
$ git commit -m "A descriptive message about your changes."
|
| 451 |
+
```
|
| 452 |
+
|
| 453 |
+
코드를 정기적으로 원본 저장소와 동기화하는 것은 좋은 아이디어입니다. 이렇게 하면 변경 사항을 빠르게 반영할 수 있습니다:
|
| 454 |
+
|
| 455 |
+
```bash
|
| 456 |
+
$ git pull upstream main
|
| 457 |
+
```
|
| 458 |
+
|
| 459 |
+
변경 사항을 계정에 푸시하려면 다음을 사용하세요:
|
| 460 |
+
|
| 461 |
+
```bash
|
| 462 |
+
$ git push -u origin a-descriptive-name-for-my-changes
|
| 463 |
+
```
|
| 464 |
+
|
| 465 |
+
6. 만족하셨다면, GitHub에서 포크한 웹페이지로 이동하여 'Pull request'를 클릭하여 변경사항을 프로젝트 메인테이너에게 검토를 요청합니다.
|
| 466 |
+
|
| 467 |
+
7. 메인테이너가 변경 사항을 요청하는 것은 괜찮습니다. 핵심 기여자들에게도 일어나는 일입니다! 따라서 변경 사항을 Pull request에서 볼 수 있도록 로컬 브랜치에서 작업하고 변경 사항을 포크에 푸시하면 자동으로 Pull request에 나타납니다.
|
| 468 |
+
|
| 469 |
+
### 테스트 [[tests]]
|
| 470 |
+
|
| 471 |
+
라이브러리 동작과 여러 예제를 테스트하기 위해 포괄적인 테스트 묶음이 포함되어 있습니다. 라이브러리 테스트는 [tests 폴더](https://github.com/huggingface/diffusers/tree/main/tests)에서 찾을 수 있습니다.
|
| 472 |
+
|
| 473 |
+
`pytest`와 `pytest-xdist`를 선호하는 이유는 더 빠르기 때문입니다. 루트 디렉토리에서 라이브러리를 위해 `pytest`로 테스트를 실행하는 방법은 다음과 같습니다:
|
| 474 |
+
|
| 475 |
+
```bash
|
| 476 |
+
$ python -m pytest -n auto --dist=loadfile -s -v ./tests/
|
| 477 |
+
```
|
| 478 |
+
|
| 479 |
+
사실, `make test`는 이렇게 구현되어 있습니다!
|
| 480 |
+
|
| 481 |
+
작업 중인 기능만 테스트하기 위해 더 작은 테스트 세트를 지정할 수 있습니다.
|
| 482 |
+
|
| 483 |
+
기본적으로 느린 테스트는 건너뜁니다. `RUN_SLOW` 환경 변수를 `yes`로 설정하여 실행할 수 있습니다. 이는 많은 기가바이트의 모델을 다운로드합니다. 충분한 디스크 공간과 좋은 인터넷 연결 또는 많은 인내심이 필요합니다!
|
| 484 |
+
|
| 485 |
+
```bash
|
| 486 |
+
$ RUN_SLOW=yes python -m pytest -n auto --dist=loadfile -s -v ./tests/
|
| 487 |
+
```
|
| 488 |
+
|
| 489 |
+
`unittest`는 완전히 지원됩니다. 다음은 `unittest`를 사용하여 테스트를 실행하는 방법입니다:
|
| 490 |
+
|
| 491 |
+
```bash
|
| 492 |
+
$ python -m unittest discover -s tests -t . -v
|
| 493 |
+
$ python -m unittest discover -s examples -t examples -v
|
| 494 |
+
```
|
| 495 |
+
|
| 496 |
+
### upstream(HuggingFace) main과 forked main 동기화하기 [[syncing-forked-main-with-upstream-huggingface-main]]
|
| 497 |
+
|
| 498 |
+
upstream 저장소에 불필요한 참조 노트를 추가하고 관련 개발자에게 알림을 보내는 것을 피하기 위해,
|
| 499 |
+
forked 저장소의 main 브랜치를 동기화할 때 다음 단계를 따르세요:
|
| 500 |
+
1. 가능한 경우, forked 저장소에서 브랜치와 PR을 사용하여 upstream과 동기화하는 것을 피하세요. 대신 forked main으로 직접 병합하세요.
|
| 501 |
+
2. PR이 절대적으로 필요한 경우, 브랜치를 체크아웃한 후 다음 단계를 사용하세요:
|
| 502 |
+
```bash
|
| 503 |
+
$ git checkout -b your-branch-for-syncing
|
| 504 |
+
$ git pull --squash --no-commit upstream main
|
| 505 |
+
$ git commit -m '<your message without GitHub references>'
|
| 506 |
+
$ git push --set-upstream origin your-branch-for-syncing
|
| 507 |
+
```
|
| 508 |
+
|
| 509 |
+
### 스타일 가이드 [[style-guide]]
|
| 510 |
+
|
| 511 |
+
Documentation string에 대해서는, 🧨 Diffusers는 [Google 스타일](https://google.github.io/styleguide/pyguide.html)을 따릅니다.
|
tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/conceptual/ethical_guidelines.md
ADDED
|
@@ -0,0 +1,64 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2024 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# 🧨 Diffusers의 윤리 지침 [[-diffusers-ethical-guidelines]]
|
| 14 |
+
|
| 15 |
+
## 서문 [[preamble]]
|
| 16 |
+
|
| 17 |
+
[Diffusers](https://huggingface.co/docs/diffusers/index)는 사전 훈련된 diffusion 모델을 제공하며 추론 및 훈련을 위한 모듈식 툴박스로 사용됩니다.
|
| 18 |
+
|
| 19 |
+
이 기술의 실제 적용과 사회에 미칠 수 있는 부정적인 영향을 고려하여 Diffusers 라이브러리의 개발, 사용자 기여 및 사용에 윤리 지침을 제공하는 것이 중요하다고 생각합니다.
|
| 20 |
+
|
| 21 |
+
이이 기술을 사용함에 따른 위험은 여전히 검토 중이지만, 몇 가지 예를 들면: 예술가들에 대한 저작권 문제; 딥 페이크의 악용; 부적절한 맥락에서의 성적 콘텐츠 생성; 동의 없는 사칭; 소수자 집단의 억압을 영속화하는 유해한 사회적 편견 등이 있습니다.
|
| 22 |
+
|
| 23 |
+
우리는 위험을 지속적으로 추적하고 커뮤니티의 응답과 소중한 피드백에 따라 다음 지침을 조정할 것입니다.
|
| 24 |
+
|
| 25 |
+
|
| 26 |
+
## 범위 [[scope]]
|
| 27 |
+
|
| 28 |
+
Diffusers 커뮤니티는 프로젝트의 개발에 다음과 같은 윤리 지침을 적용하며, 특히 윤리적 문제와 관련된 민감한 주제에 대한 커뮤니티의 기여를 조정하는 데 도움을 줄 것입니다.
|
| 29 |
+
|
| 30 |
+
|
| 31 |
+
## 윤리 지침 [[ethical-guidelines]]
|
| 32 |
+
|
| 33 |
+
다음 윤리 지침은 일반적으로 적용되지만, 민감한 윤리적 문제와 관련하여 기술적 선택을 할 때 이를 우선적으로 적용할 것입니다. 나아가, 해당 기술의 최신 동향과 관련된 새로운 위험이 발생함에 따라 이러한 윤리 원칙을 조정할 것을 약속드립니다.
|
| 34 |
+
|
| 35 |
+
- **투명성**: 우리는 PR을 관리하고, 사용자에게 우리의 선택을 설명하며, 기술적 의사결정을 내릴 때 투명성을 유지할 것을 약속합니다.
|
| 36 |
+
|
| 37 |
+
- **일관성**: 우리는 프로젝트 관리에서 사용자들에게 동일한 수준의 관심을 보장하고 기술적으로 안정되고 일관된 상태를 유지할 것을 약속합니다.
|
| 38 |
+
|
| 39 |
+
- **간결성**: Diffusers 라이브러리를 사용하고 활용하기 쉽게 만들기 위해, 프로젝트의 목표를 간결하고 일관성 있게 유지할 것을 약속합니다.
|
| 40 |
+
|
| 41 |
+
- **접근성**: Diffusers 프로젝트는 기술적 전문 지식 없어도 프로젝트 운영에 참여할 수 있는 기여자의 진입장벽을 낮춥니다. 이를 통해 연구 결과물이 커뮤니티에 더 잘 접근할 수 있게 됩니다.
|
| 42 |
+
|
| 43 |
+
- **재현성**: 우리는 Diffusers 라이브러리를 통해 제공되는 업스트림(upstream) 코드, 모델 및 데이터셋의 재현성에 대해 투명하게 공개할 것을 목표로 합니다.
|
| 44 |
+
|
| 45 |
+
- **책임**: 우리는 커뮤니티와 팀워크를 통해, 이 기술의 잠재적인 위험과 위험을 예측하고 완화하는 데 대한 공동 책임을 가지고 있습니다.
|
| 46 |
+
|
| 47 |
+
|
| 48 |
+
## 구현 사례: 안전 기능과 메커니즘 [[examples-of-implementations-safety-features-and-mechanisms]]
|
| 49 |
+
|
| 50 |
+
팀은 diffusion 기술과 관련된 잠재적인 윤리 및 사회적 위험에 대처하기 위한 기술적 및 비기술적 도구를 제공하고자 하고 있습니다. 또한, 커뮤니티의 참여는 이러한 기능의 구현하고 우리와 함께 인식을 높이는 데 매우 중요합니다.
|
| 51 |
+
|
| 52 |
+
- [**커뮤니티 탭**](https://huggingface.co/docs/hub/repositories-pull-requests-discussions): 이를 통해 커뮤니티는 프로젝트에 대해 토론하고 더 나은 협력을 할 수 있습니다.
|
| 53 |
+
|
| 54 |
+
- **편향 탐색 및 평가**: Hugging Face 팀은 Stable Diffusion 모델의 편향성을 대화형으로 보여주는 [space](https://huggingface.co/spaces/society-ethics/DiffusionBiasExplorer)을 제공합니다. 이런 의미에서, 우리는 편향 탐색 및 평가를 지원하고 장려합니다.
|
| 55 |
+
|
| 56 |
+
- **배포에서의 안전 유도**
|
| 57 |
+
|
| 58 |
+
- [**안전한 Stable Diffusion**](https://huggingface.co/docs/diffusers/main/en/api/pipelines/stable_diffusion/stable_diffusion_safe): 이는 필터되지 않은 웹 크롤링 데이터셋으로 훈련된 Stable Diffusion과 같은 모델이 부적절한 변질에 취약한 문제를 완화합니다. 관련 논문: [Safe Latent Diffusion: Mitigating Inappropriate Degeneration in Diffusion Models](https://huggingface.co/papers/2211.05105).
|
| 59 |
+
|
| 60 |
+
- [**안전 검사기**](https://github.com/huggingface/diffusers/blob/main/src/diffusers/pipelines/stable_diffusion/safety_checker.py): 이미지가 생성된 후에 이미자가 임베��� 공간에서 일련의 하드코딩된 유해 개념의 클래스일 확률을 확인하고 비교합니다. 유해 개념은 역공학을 방지하기 위해 의도적으로 숨겨져 있습니다.
|
| 61 |
+
|
| 62 |
+
- **Hub에서의 단계적인 배포**: 특히 민감한 상황에서는 일부 리포지토리에 대한 접근을 제한해야 합니다. 이 단계적인 배포는 중간 단계로, 리포지토리 작성자가 사용에 대한 더 많은 통제력을 갖게 합니다.
|
| 63 |
+
|
| 64 |
+
- **라이선싱**: [OpenRAILs](https://huggingface.co/blog/open_rail)와 같은 새로운 유형의 라이선싱을 통해 자유로운 접근을 보장하면서도 더 책임 있는 사용을 위한 일련의 제한을 둘 수 있습니다.
|
tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/conceptual/evaluation.md
ADDED
|
@@ -0,0 +1,554 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2024 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Diffusion 모델 평가하기[[evaluating-diffusion-models]]
|
| 14 |
+
|
| 15 |
+
<a target="_blank" href="https://colab.research.google.com/github/huggingface/notebooks/blob/main/diffusers/evaluation.ipynb">
|
| 16 |
+
<img src="https://colab.research.google.com/assets/colab-badge.svg" alt="Open In Colab"/>
|
| 17 |
+
</a>
|
| 18 |
+
|
| 19 |
+
[Stable Diffusion](https://huggingface.co/docs/diffusers/stable_diffusion)와 같은 생성 모델의 평가는 주관적인 성격을 가지고 있습니다. 그러나 실무자와 연구자로서 우리는 종종 다양한 가능성 중에서 신중한 선택을 해야 합니다. 그래서 다양한 생성 모델 (GAN, Diffusion 등)을 사용할 때 어떻게 선택해야 할까요?
|
| 20 |
+
|
| 21 |
+
정성적인 평가는 모델의 이미지 품질에 대한 주관적인 평가이므로 오류가 발생할 수 있고 결정에 잘못된 영향을 미칠 수 있습니다. 반면, 정량적인 평가는 이미지 품질과 직접적인 상관관계를 갖지 않을 수 있습니다. 따라서 일반적으로 정성적 평가와 정량적 평가를 모두 고려하는 것이 더 강력한 신호를 제공하여 모델 선택에 도움이 됩니다.
|
| 22 |
+
|
| 23 |
+
이 문서에서는 Diffusion 모델을 평가하기 위한 정성적 및 정량적 방법에 대해 상세히 설명합니다. 정량적 방법에 대해서는 특히 `diffusers`와 함께 구현하는 방법에 초점을 맞추었습니다.
|
| 24 |
+
|
| 25 |
+
이 문서에서 보여진 방법들은 기반 생성 모델을 고정시키고 다양한 [노이즈 스케줄러](https://huggingface.co/docs/diffusers/main/en/api/schedulers/overview)를 평가하는 데에도 사용할 수 있습니다.
|
| 26 |
+
|
| 27 |
+
## 시나리오[[scenarios]]
|
| 28 |
+
다음과 같은 파이프라인을 사용하여 Diffusion 모델을 다룹니다:
|
| 29 |
+
|
| 30 |
+
- 텍스트로 안내된 이미지 생성 (예: [`StableDiffusionPipeline`](https://huggingface.co/docs/diffusers/main/en/api/pipelines/stable_diffusion/text2img)).
|
| 31 |
+
- 입력 이미지에 추가로 조건을 건 텍스트로 안내된 이미지 생성 (예: [`StableDiffusionImg2ImgPipeline`](https://huggingface.co/docs/diffusers/main/en/api/pipelines/stable_diffusion/img2img) 및 [`StableDiffusionInstructPix2PixPipeline`](https://huggingface.co/docs/diffusers/main/en/api/pipelines/pix2pix)).
|
| 32 |
+
- 클래스 조건화된 이미지 생성 모델 (예: [`DiTPipeline`](https://huggingface.co/docs/diffusers/main/en/api/pipelines/dit)).
|
| 33 |
+
|
| 34 |
+
## 정성적 평가[[qualitative-evaluation]]
|
| 35 |
+
|
| 36 |
+
정성적 평가는 일반적으로 생성된 이미지의 인간 평가를 포함합니다. 품질은 구성성, 이미지-텍스트 일치, 공간 관계 등과 같은 측면에서 측정됩니다. 일반적인 프롬프트는 주관적인 지표에 대한 일정한 기준을 제공합니다.
|
| 37 |
+
DrawBench와 PartiPrompts는 정성적인 벤치마킹에 사용되는 프롬프트 데이터셋입니다. DrawBench와 PartiPrompts는 각각 [Imagen](https://imagen.research.google/)과 [Parti](https://parti.research.google/)에서 소개되었습니다.
|
| 38 |
+
|
| 39 |
+
[Parti 공식 웹사이트](https://parti.research.google/)에서 다음과 같이 설명하고 있습니다:
|
| 40 |
+
|
| 41 |
+
> PartiPrompts (P2)는 이 작업의 일부로 공개되는 영어로 된 1600개 이상의 다양한 프롬프트 세트입니다. P2는 다양한 범주와 도전 측면에서 모델의 능력을 측정하는 데 사용할 수 있습니다.
|
| 42 |
+
|
| 43 |
+
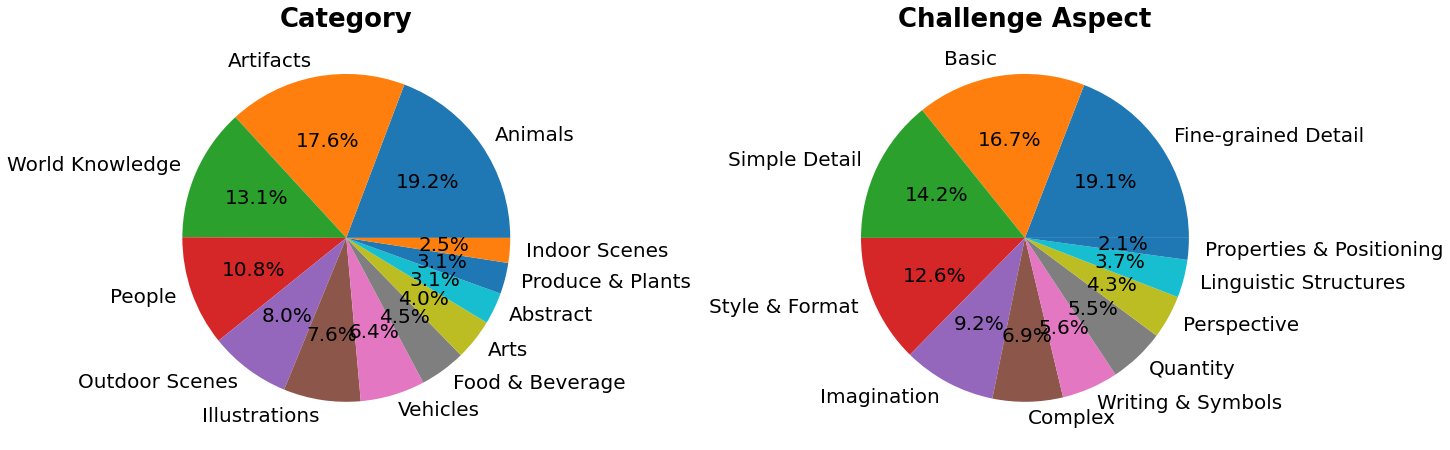
|
| 44 |
+
|
| 45 |
+
PartiPrompts는 다음과 같은 열을 가지고 있습니다:
|
| 46 |
+
|
| 47 |
+
- 프롬프트 (Prompt)
|
| 48 |
+
- 프롬프트의 카테고리 (예: "Abstract", "World Knowledge" 등)
|
| 49 |
+
- 난이도를 반영한 챌린지 (예: "Basic", "Complex", "Writing & Symbols" 등)
|
| 50 |
+
|
| 51 |
+
이러한 벤치마크는 서로 다른 이미지 생성 모델을 인간 평가로 비교할 수 있도록 합니다.
|
| 52 |
+
|
| 53 |
+
이를 위해 🧨 Diffusers 팀은 **Open Parti Prompts**를 구축했습니다. 이는 Parti Prompts를 기반으로 한 커뮤니티 기반의 질적 벤치마크로, 최첨단 오픈 소스 확산 모델을 비교하는 데 사용됩니다:
|
| 54 |
+
- [Open Parti Prompts 게임](https://huggingface.co/spaces/OpenGenAI/open-parti-prompts): 10개의 parti prompt에 대해 4개의 생성된 이미지가 제시되며, 사용자는 프롬프트에 가장 적합한 이미지를 선택합니다.
|
| 55 |
+
- [Open Parti Prompts 리더보드](https://huggingface.co/spaces/OpenGenAI/parti-prompts-leaderboard): 현재 최고의 오픈 소스 diffusion 모델들을 서로 비교하는 리더보드입니다.
|
| 56 |
+
|
| 57 |
+
이미지를 수동으로 비교하려면, `diffusers`를 사용하여 몇가지 PartiPrompts를 어떻게 활용할 수 있는지 알아봅시다.
|
| 58 |
+
|
| 59 |
+
다음은 몇 가지 다른 도전에서 샘플링한 프롬프트를 보여줍니다: Basic, Complex, Linguistic Structures, Imagination, Writing & Symbols. 여기서는 PartiPrompts를 [데이터셋](https://huggingface.co/datasets/nateraw/parti-prompts)으로 사용합니다.
|
| 60 |
+
|
| 61 |
+
```python
|
| 62 |
+
from datasets import load_dataset
|
| 63 |
+
|
| 64 |
+
# prompts = load_dataset("nateraw/parti-prompts", split="train")
|
| 65 |
+
# prompts = prompts.shuffle()
|
| 66 |
+
# sample_prompts = [prompts[i]["Prompt"] for i in range(5)]
|
| 67 |
+
|
| 68 |
+
# Fixing these sample prompts in the interest of reproducibility.
|
| 69 |
+
sample_prompts = [
|
| 70 |
+
"a corgi",
|
| 71 |
+
"a hot air balloon with a yin-yang symbol, with the moon visible in the daytime sky",
|
| 72 |
+
"a car with no windows",
|
| 73 |
+
"a cube made of porcupine",
|
| 74 |
+
'The saying "BE EXCELLENT TO EACH OTHER" written on a red brick wall with a graffiti image of a green alien wearing a tuxedo. A yellow fire hydrant is on a sidewalk in the foreground.',
|
| 75 |
+
]
|
| 76 |
+
```
|
| 77 |
+
이제 이런 프롬프트를 사용하여 Stable Diffusion ([v1-4 checkpoint](https://huggingface.co/CompVis/stable-diffusion-v1-4))를 사용한 이미지 생성을 할 수 있습니다 :
|
| 78 |
+
|
| 79 |
+
```python
|
| 80 |
+
import torch
|
| 81 |
+
|
| 82 |
+
seed = 0
|
| 83 |
+
generator = torch.manual_seed(seed)
|
| 84 |
+
|
| 85 |
+
images = sd_pipeline(sample_prompts, num_images_per_prompt=1, generator=generator).images
|
| 86 |
+
```
|
| 87 |
+
|
| 88 |
+
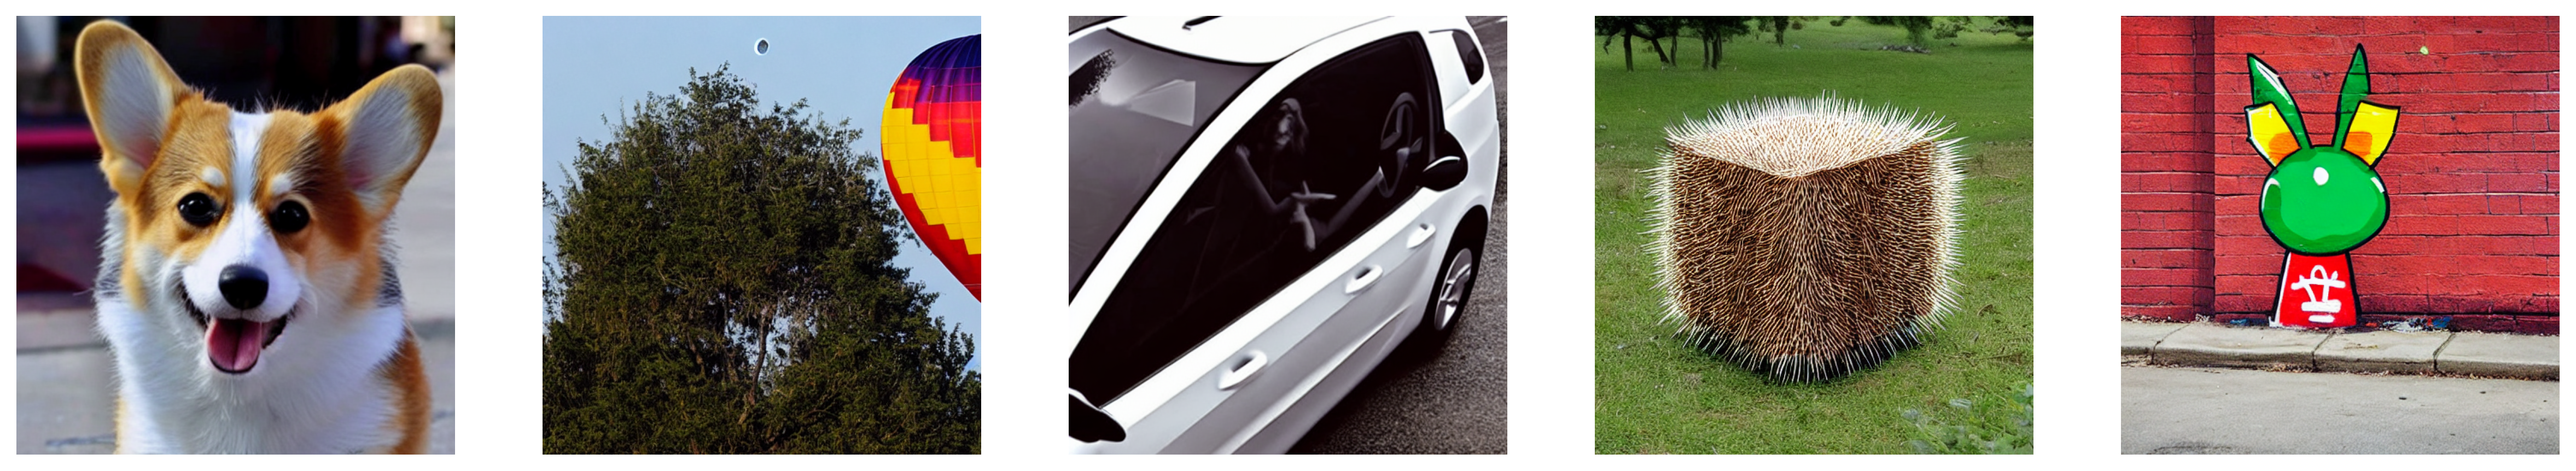
|
| 89 |
+
|
| 90 |
+
|
| 91 |
+
`num_images_per_prompt`를 설정하여 동일한 프롬프트에 대해 다른 이미지를 비교할 수도 있습니다. 다른 체크포인트([v1-5](https://huggingface.co/stable-diffusion-v1-5/stable-diffusion-v1-5))로 동일한 파이프라인을 실행하면 다음과 같은 결과가 나옵니다:
|
| 92 |
+
|
| 93 |
+
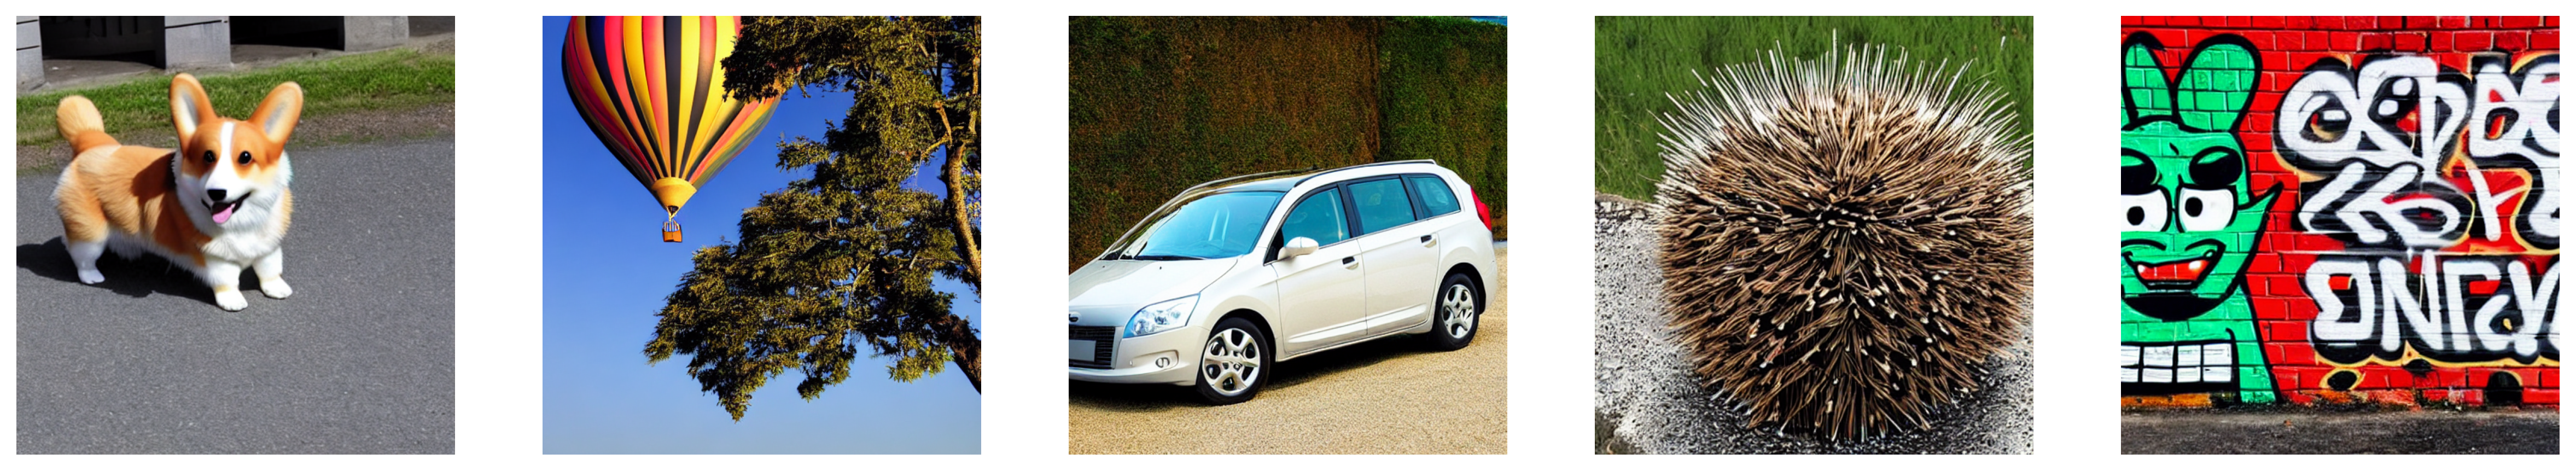
|
| 94 |
+
|
| 95 |
+
|
| 96 |
+
다양한 모델을 사용하여 모든 프롬프트에서 생성된 여러 이미지들이 생성되면 (평가 과정에서) 이러한 결과물들은 사람 평가자들에게 점수를 매기기 위해 제시됩니다. DrawBench와 PartiPrompts 벤치마크에 대한 자세한 내용은 각각의 논문을 참조하십시오.
|
| 97 |
+
|
| 98 |
+
<Tip>
|
| 99 |
+
|
| 100 |
+
모델이 훈련 중일 때 추론 샘플을 살펴보는 것은 훈련 진행 상황을 측정하는 데 유용합니다. [훈련 스크립트](https://github.com/huggingface/diffusers/tree/main/examples/)에서는 TensorBoard와 Weights & Biases에 대한 추가 지원과 함께 이 유틸리티를 지원합니다.
|
| 101 |
+
|
| 102 |
+
</Tip>
|
| 103 |
+
|
| 104 |
+
## 정량적 평가[[quantitative-evaluation]]
|
| 105 |
+
|
| 106 |
+
이 섹션에서는 세 가지 다른 확산 파이프라인을 평가하는 방법을 안내합니다:
|
| 107 |
+
|
| 108 |
+
- CLIP 점수
|
| 109 |
+
- CLIP 방향성 유사도
|
| 110 |
+
- FID
|
| 111 |
+
|
| 112 |
+
### 텍스트 안내 이미지 생성[[text-guided-image-generation]]
|
| 113 |
+
|
| 114 |
+
[CLIP 점수](https://huggingface.co/papers/2104.08718)는 이미지-캡션 쌍의 호환성을 측정합니다. 높은 CLIP 점수는 높은 호환성🔼을 나타냅니다. CLIP 점수는 이미지와 캡션 사이의 의미적 유사성으로 생각할 수도 있습니다. CLIP 점수는 인간 판단과 높은 상관관계를 가지고 있습니다.
|
| 115 |
+
|
| 116 |
+
[`StableDiffusionPipeline`]을 일단 로드해봅시다:
|
| 117 |
+
|
| 118 |
+
```python
|
| 119 |
+
from diffusers import StableDiffusionPipeline
|
| 120 |
+
import torch
|
| 121 |
+
|
| 122 |
+
model_ckpt = "CompVis/stable-diffusion-v1-4"
|
| 123 |
+
sd_pipeline = StableDiffusionPipeline.from_pretrained(model_ckpt, torch_dtype=torch.float16).to("cuda")
|
| 124 |
+
```
|
| 125 |
+
|
| 126 |
+
여러 개의 프롬프트를 사용하여 이미지를 생성합니다:
|
| 127 |
+
|
| 128 |
+
```python
|
| 129 |
+
prompts = [
|
| 130 |
+
"a photo of an astronaut riding a horse on mars",
|
| 131 |
+
"A high tech solarpunk utopia in the Amazon rainforest",
|
| 132 |
+
"A pikachu fine dining with a view to the Eiffel Tower",
|
| 133 |
+
"A mecha robot in a favela in expressionist style",
|
| 134 |
+
"an insect robot preparing a delicious meal",
|
| 135 |
+
"A small cabin on top of a snowy mountain in the style of Disney, artstation",
|
| 136 |
+
]
|
| 137 |
+
|
| 138 |
+
images = sd_pipeline(prompts, num_images_per_prompt=1, output_type="np").images
|
| 139 |
+
|
| 140 |
+
print(images.shape)
|
| 141 |
+
# (6, 512, 512, 3)
|
| 142 |
+
```
|
| 143 |
+
|
| 144 |
+
그러고 나서 CLIP 점수를 계산합니다.
|
| 145 |
+
|
| 146 |
+
```python
|
| 147 |
+
from torchmetrics.functional.multimodal import clip_score
|
| 148 |
+
from functools import partial
|
| 149 |
+
|
| 150 |
+
clip_score_fn = partial(clip_score, model_name_or_path="openai/clip-vit-base-patch16")
|
| 151 |
+
|
| 152 |
+
def calculate_clip_score(images, prompts):
|
| 153 |
+
images_int = (images * 255).astype("uint8")
|
| 154 |
+
clip_score = clip_score_fn(torch.from_numpy(images_int).permute(0, 3, 1, 2), prompts).detach()
|
| 155 |
+
return round(float(clip_score), 4)
|
| 156 |
+
|
| 157 |
+
sd_clip_score = calculate_clip_score(images, prompts)
|
| 158 |
+
print(f"CLIP score: {sd_clip_score}")
|
| 159 |
+
# CLIP score: 35.7038
|
| 160 |
+
```
|
| 161 |
+
|
| 162 |
+
위의 예제에서는 각 프롬프트 당 하나의 이미지를 생성했습니다. 만약 프롬프트 당 여러 이미지를 생성한다면, 프롬프트 당 생성된 ��미지의 평균 점수를 사용해야 합니다.
|
| 163 |
+
|
| 164 |
+
이제 [`StableDiffusionPipeline`]과 호환되는 두 개의 체크포인트를 비교하려면, 파이프라인을 호출할 때 generator를 전달해야 합니다. 먼저, 고정된 시드로 [v1-4 Stable Diffusion 체크포인트](https://huggingface.co/CompVis/stable-diffusion-v1-4)를 사용하여 이미지를 생성합니다:
|
| 165 |
+
|
| 166 |
+
```python
|
| 167 |
+
seed = 0
|
| 168 |
+
generator = torch.manual_seed(seed)
|
| 169 |
+
|
| 170 |
+
images = sd_pipeline(prompts, num_images_per_prompt=1, generator=generator, output_type="np").images
|
| 171 |
+
```
|
| 172 |
+
|
| 173 |
+
그런 다음 [v1-5 checkpoint](https://huggingface.co/stable-diffusion-v1-5/stable-diffusion-v1-5)를 로드하여 이미지를 생성합니다:
|
| 174 |
+
|
| 175 |
+
```python
|
| 176 |
+
model_ckpt_1_5 = "stable-diffusion-v1-5/stable-diffusion-v1-5"
|
| 177 |
+
sd_pipeline_1_5 = StableDiffusionPipeline.from_pretrained(model_ckpt_1_5, torch_dtype=weight_dtype).to(device)
|
| 178 |
+
|
| 179 |
+
images_1_5 = sd_pipeline_1_5(prompts, num_images_per_prompt=1, generator=generator, output_type="np").images
|
| 180 |
+
```
|
| 181 |
+
|
| 182 |
+
그리고 마지막으로 CLIP 점수를 비교합니다:
|
| 183 |
+
|
| 184 |
+
```python
|
| 185 |
+
sd_clip_score_1_4 = calculate_clip_score(images, prompts)
|
| 186 |
+
print(f"CLIP Score with v-1-4: {sd_clip_score_1_4}")
|
| 187 |
+
# CLIP Score with v-1-4: 34.9102
|
| 188 |
+
|
| 189 |
+
sd_clip_score_1_5 = calculate_clip_score(images_1_5, prompts)
|
| 190 |
+
print(f"CLIP Score with v-1-5: {sd_clip_score_1_5}")
|
| 191 |
+
# CLIP Score with v-1-5: 36.2137
|
| 192 |
+
```
|
| 193 |
+
|
| 194 |
+
[v1-5](https://huggingface.co/stable-diffusion-v1-5/stable-diffusion-v1-5) 체크포인트가 이전 버전보다 더 나은 성능을 보이는 것 같습니다. 그러나 CLIP 점수를 계산하기 위해 사용한 프롬프트의 수가 상당히 적습니다. 보다 실용적인 평가를 위해서는 이 수를 훨씬 높게 설정하고, 프롬프트를 다양하게 사용해야 합니다.
|
| 195 |
+
|
| 196 |
+
<Tip warning={true}>
|
| 197 |
+
|
| 198 |
+
이 점수에는 몇 가지 제한 사항이 있습니다. 훈련 데이터셋의 캡션은 웹에서 크롤링되어 이미지와 관련된 `alt` 및 유사한 태그에서 추출되었습니다. 이들은 인간이 이미지를 설명하는 데 사용할 수 있는 것과 일치하지 않을 수 있습니다. 따라서 여기서는 몇 가지 프롬프트를 "엔지니어링"해야 했습니다.
|
| 199 |
+
|
| 200 |
+
</Tip>
|
| 201 |
+
|
| 202 |
+
### 이미지 조건화된 텍스트-이미지 생성[[image-conditioned-text-to-image-generation]]
|
| 203 |
+
|
| 204 |
+
이 경우, 생성 파이프라인을 입력 이미지와 텍스트 프롬프트로 조건화합니다. [`StableDiffusionInstructPix2PixPipeline`]을 예로 들어보겠습니다. 이는 편집 지시문을 입력 프롬프트로 사용하고 편집할 입력 이미지를 사용합니다.
|
| 205 |
+
|
| 206 |
+
다음은 하나의 예시입니다:
|
| 207 |
+
|
| 208 |
+
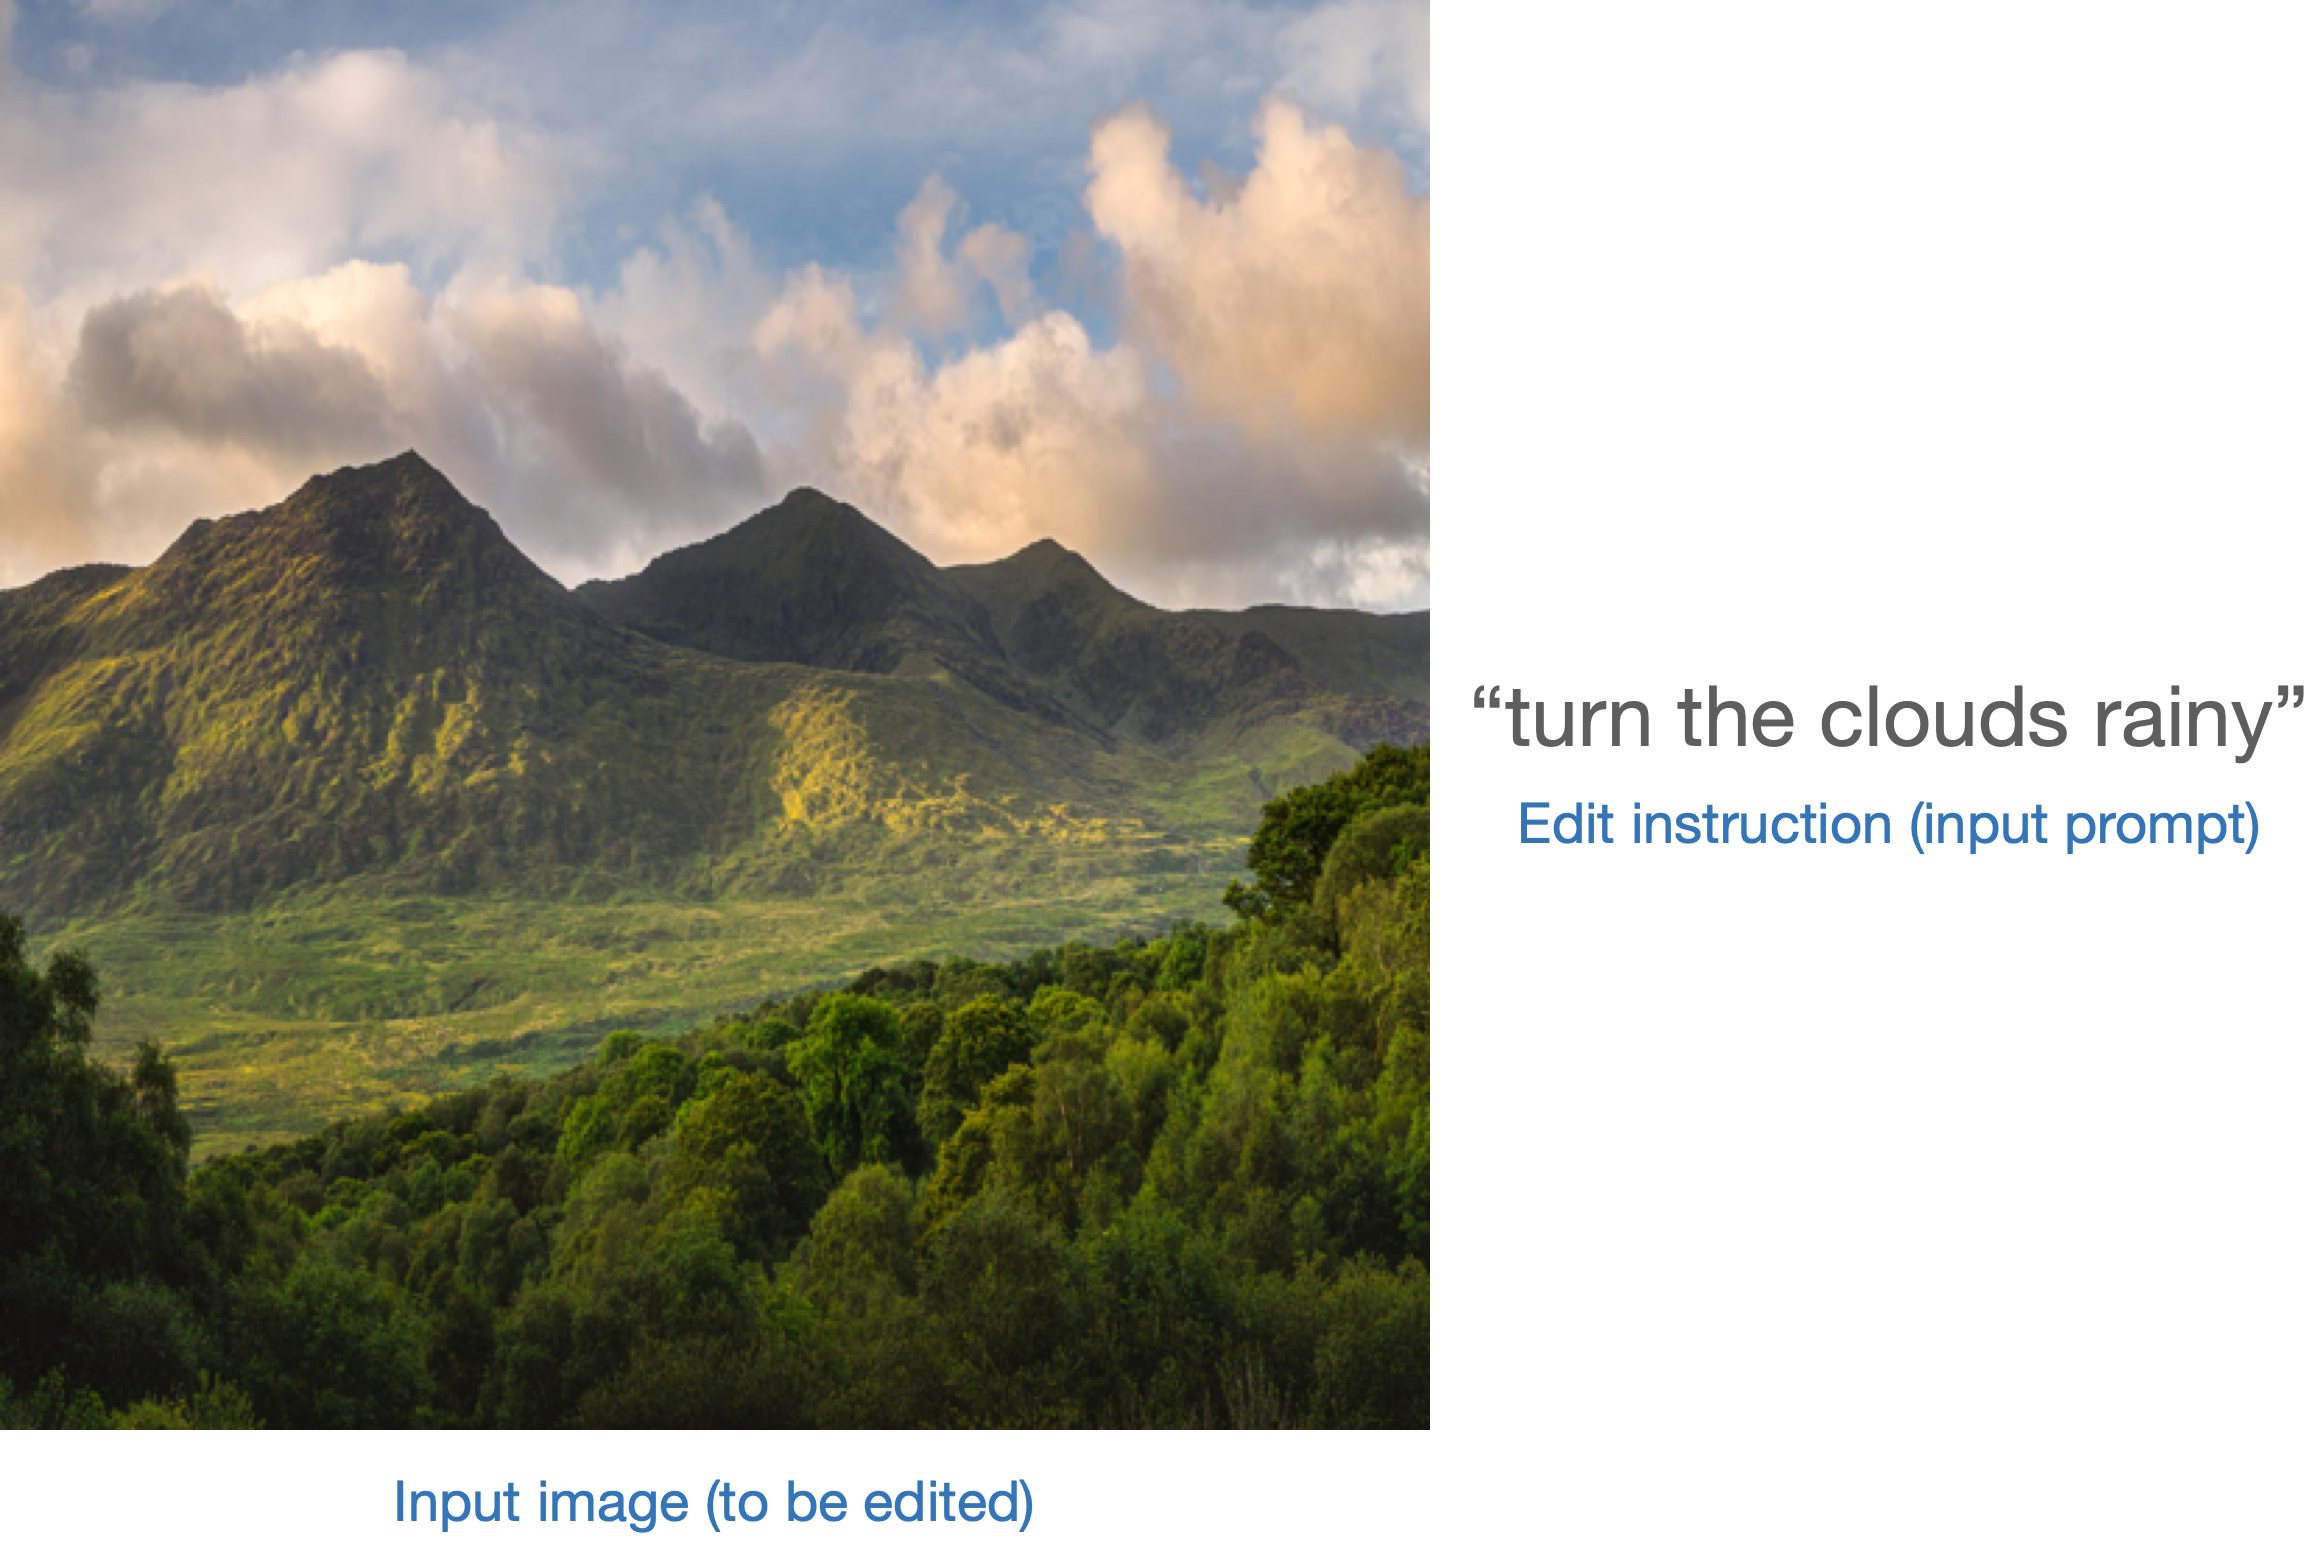
|
| 209 |
+
|
| 210 |
+
모델을 평가하는 한 가지 전략은 두 이미지 캡션 간의 변경과([CLIP-Guided Domain Adaptation of Image Generators](https://huggingface.co/papers/2108.00946)에서 보여줍니다) 함께 두 이미지 사이의 변경의 일관성을 측정하는 것입니다 ([CLIP](https://huggingface.co/docs/transformers/model_doc/clip) 공간에서). 이를 "**CLIP 방향성 유사성**"이라고 합니다.
|
| 211 |
+
|
| 212 |
+
- 캡션 1은 편집할 이미지 (이미지 1)에 해당합니다.
|
| 213 |
+
- 캡션 2는 편집된 이미지 (이미지 2)에 해당합니다. 편집 지시를 반영해야 합니다.
|
| 214 |
+
|
| 215 |
+
다음은 그림으로 된 개요입니다:
|
| 216 |
+
|
| 217 |
+
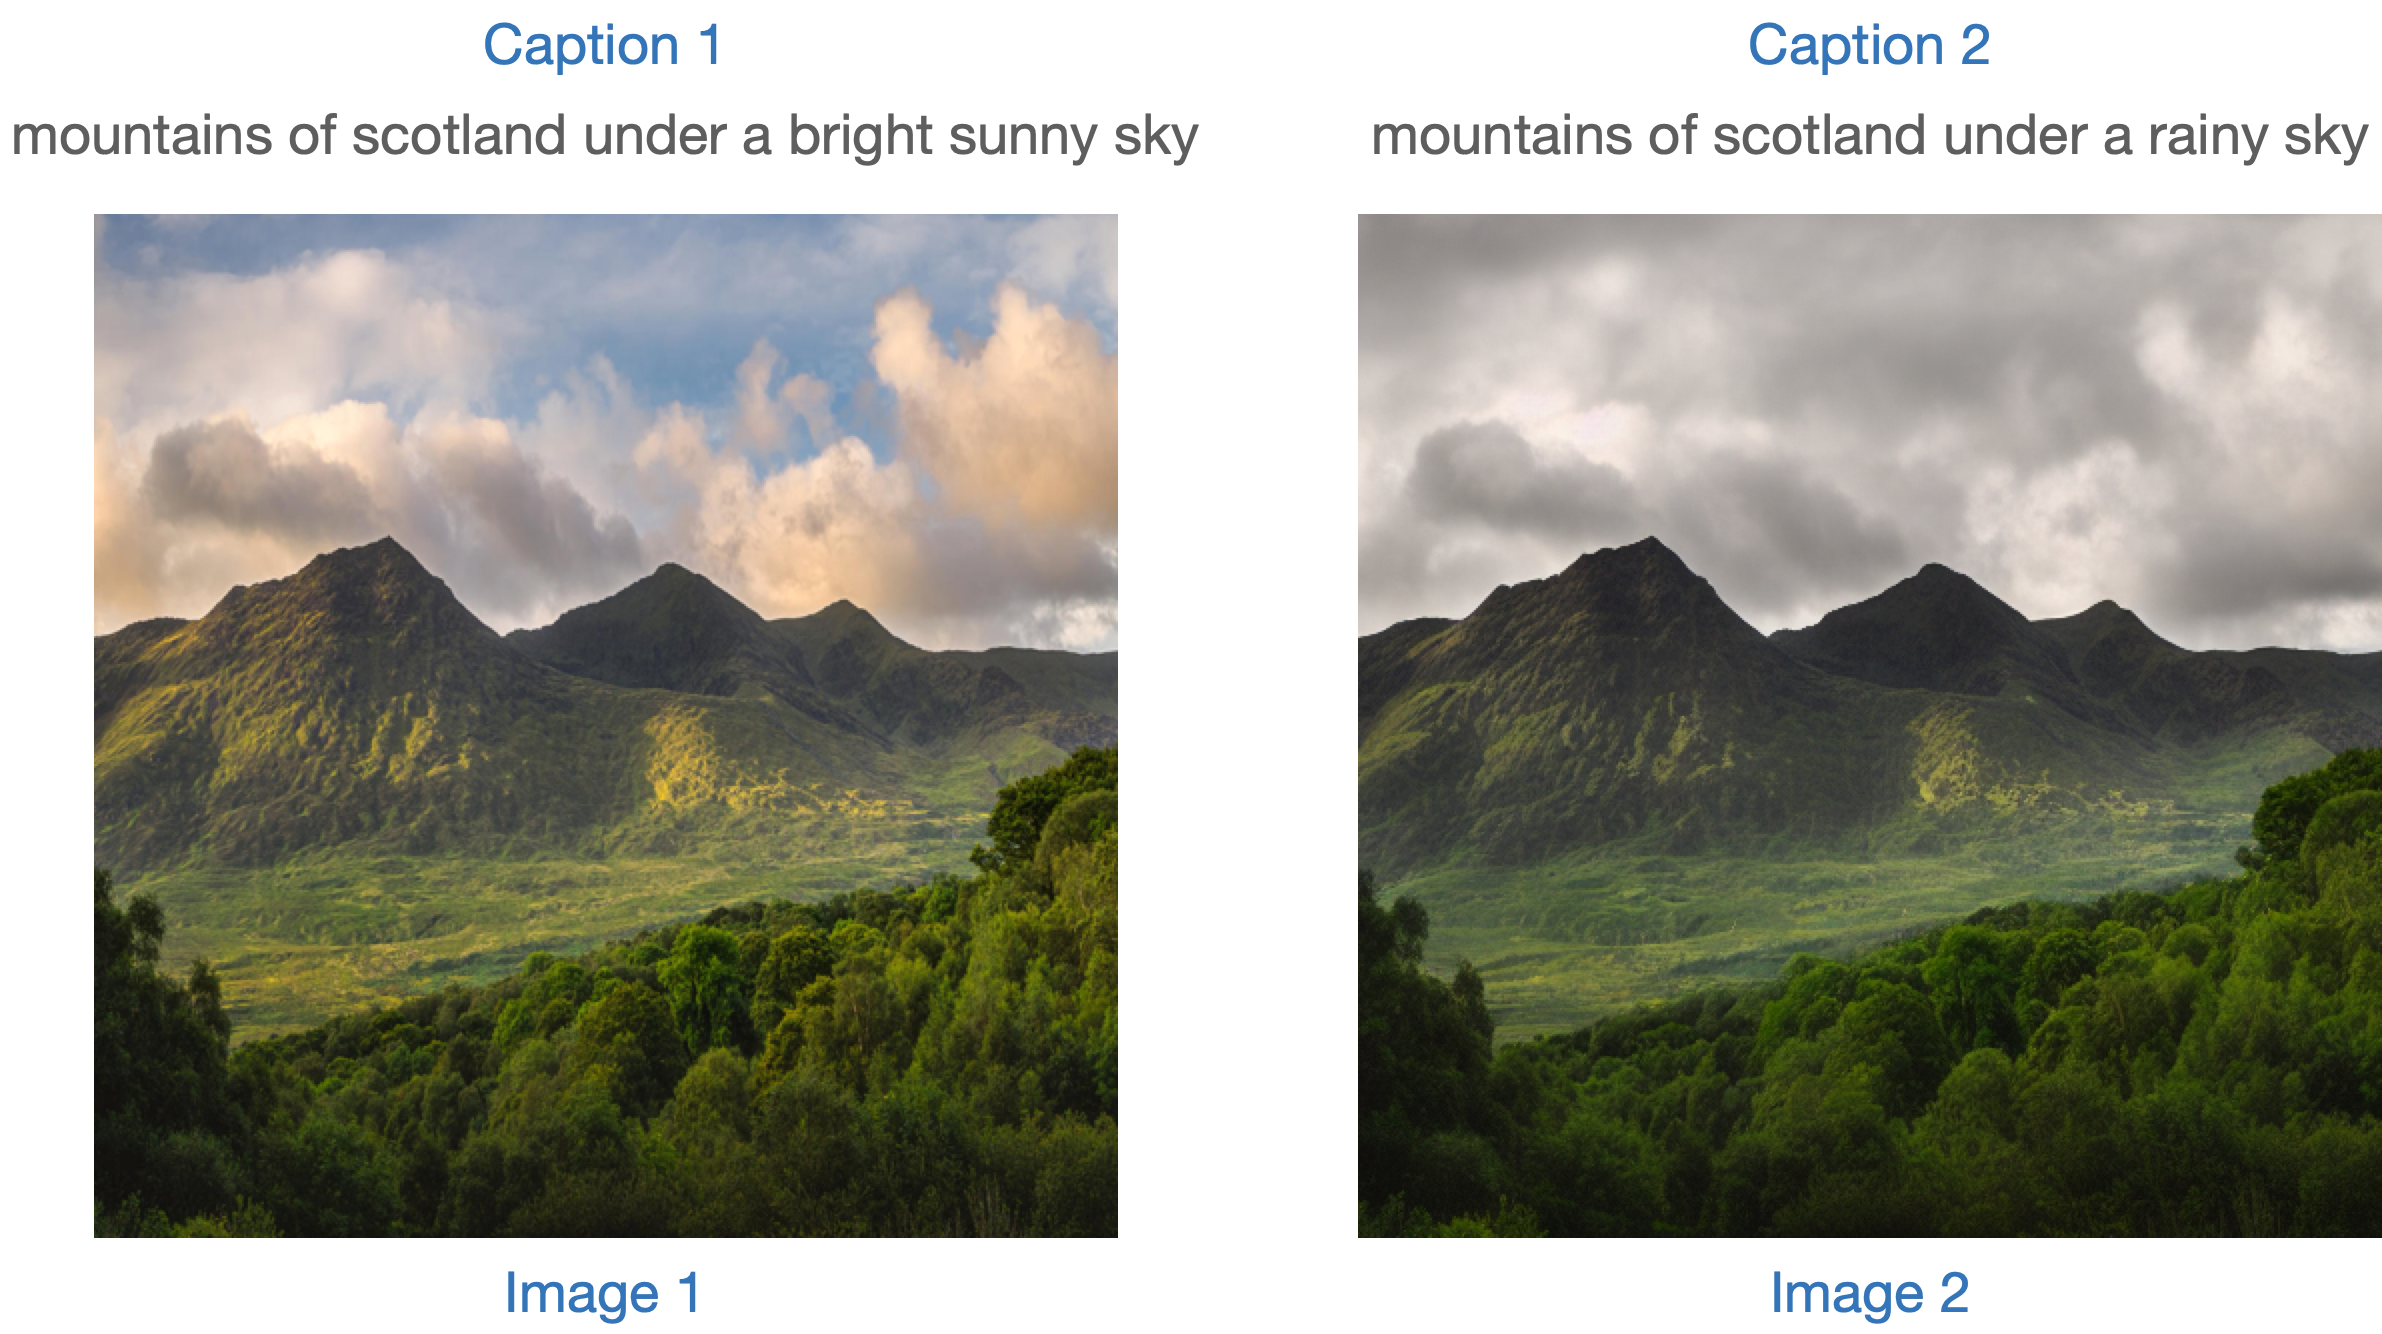
|
| 218 |
+
|
| 219 |
+
우리는 이 측정 항목을 구현하기 위해 미니 데이터 세트를 준비했습니다. 먼저 데이터 세트를 로드해 보겠습니다.
|
| 220 |
+
|
| 221 |
+
```python
|
| 222 |
+
from datasets import load_dataset
|
| 223 |
+
|
| 224 |
+
dataset = load_dataset("sayakpaul/instructpix2pix-demo", split="train")
|
| 225 |
+
dataset.features
|
| 226 |
+
```
|
| 227 |
+
|
| 228 |
+
```bash
|
| 229 |
+
{'input': Value(dtype='string', id=None),
|
| 230 |
+
'edit': Value(dtype='string', id=None),
|
| 231 |
+
'output': Value(dtype='string', id=None),
|
| 232 |
+
'image': Image(decode=True, id=None)}
|
| 233 |
+
```
|
| 234 |
+
|
| 235 |
+
여기에는 다음과 같은 항목이 있습니다:
|
| 236 |
+
|
| 237 |
+
- `input`은 `image`에 해당하는 캡션입니다.
|
| 238 |
+
- `edit`은 편집 지시사항을 나타냅니다.
|
| 239 |
+
- `output`은 `edit` 지시사항을 반영한 수정된 캡션입니다.
|
| 240 |
+
|
| 241 |
+
샘플을 살펴보겠습니다.
|
| 242 |
+
|
| 243 |
+
```python
|
| 244 |
+
idx = 0
|
| 245 |
+
print(f"Original caption: {dataset[idx]['input']}")
|
| 246 |
+
print(f"Edit instruction: {dataset[idx]['edit']}")
|
| 247 |
+
print(f"Modified caption: {dataset[idx]['output']}")
|
| 248 |
+
```
|
| 249 |
+
|
| 250 |
+
```bash
|
| 251 |
+
Original caption: 2. FAROE ISLANDS: An archipelago of 18 mountainous isles in the North Atlantic Ocean between Norway and Iceland, the Faroe Islands has 'everything you could hope for', according to Big 7 Travel. It boasts 'crystal clear waterfalls, rocky cliffs that seem to jut out of nowhere and velvety green hills'
|
| 252 |
+
Edit instruction: make the isles all white marble
|
| 253 |
+
Modified caption: 2. WHITE MARBLE ISLANDS: An archipelago of 18 mountainous white marble isles in the North Atlantic Ocean between Norway and Iceland, the White Marble Islands has 'everything you could hope for', according to Big 7 Travel. It boasts 'crystal clear waterfalls, rocky cliffs that seem to jut out of nowhere and velvety green hills'
|
| 254 |
+
```
|
| 255 |
+
|
| 256 |
+
다음은 이미지입니다:
|
| 257 |
+
|
| 258 |
+
```python
|
| 259 |
+
dataset[idx]["image"]
|
| 260 |
+
```
|
| 261 |
+
|
| 262 |
+
|
| 263 |
+
|
| 264 |
+
먼저 편집 지시사항을 사용하여 데이터 세트의 이미지를 편집하고 방향 유사도를 계산합니다.
|
| 265 |
+
|
| 266 |
+
[`StableDiffusionInstructPix2PixPipeline`]를 먼저 로드합니다:
|
| 267 |
+
|
| 268 |
+
```python
|
| 269 |
+
from diffusers import StableDiffusionInstructPix2PixPipeline
|
| 270 |
+
|
| 271 |
+
instruct_pix2pix_pipeline = StableDiffusionInstructPix2PixPipeline.from_pretrained(
|
| 272 |
+
"timbrooks/instruct-pix2pix", torch_dtype=torch.float16
|
| 273 |
+
).to(device)
|
| 274 |
+
```
|
| 275 |
+
|
| 276 |
+
이제 편집을 수행합니다:
|
| 277 |
+
|
| 278 |
+
```python
|
| 279 |
+
import numpy as np
|
| 280 |
+
|
| 281 |
+
|
| 282 |
+
def edit_image(input_image, instruction):
|
| 283 |
+
image = instruct_pix2pix_pipeline(
|
| 284 |
+
instruction,
|
| 285 |
+
image=input_image,
|
| 286 |
+
output_type="np",
|
| 287 |
+
generator=generator,
|
| 288 |
+
).images[0]
|
| 289 |
+
return image
|
| 290 |
+
|
| 291 |
+
input_images = []
|
| 292 |
+
original_captions = []
|
| 293 |
+
modified_captions = []
|
| 294 |
+
edited_images = []
|
| 295 |
+
|
| 296 |
+
for idx in range(len(dataset)):
|
| 297 |
+
input_image = dataset[idx]["image"]
|
| 298 |
+
edit_instruction = dataset[idx]["edit"]
|
| 299 |
+
edited_image = edit_image(input_image, edit_instruction)
|
| 300 |
+
|
| 301 |
+
input_images.append(np.array(input_image))
|
| 302 |
+
original_captions.append(dataset[idx]["input"])
|
| 303 |
+
modified_captions.append(dataset[idx]["output"])
|
| 304 |
+
edited_images.append(edited_image)
|
| 305 |
+
```
|
| 306 |
+
방향 유사도를 계산하기 위해서는 먼저 CLIP의 이미지와 텍스트 인코더를 로드합니다:
|
| 307 |
+
|
| 308 |
+
```python
|
| 309 |
+
from transformers import (
|
| 310 |
+
CLIPTokenizer,
|
| 311 |
+
CLIPTextModelWithProjection,
|
| 312 |
+
CLIPVisionModelWithProjection,
|
| 313 |
+
CLIPImageProcessor,
|
| 314 |
+
)
|
| 315 |
+
|
| 316 |
+
clip_id = "openai/clip-vit-large-patch14"
|
| 317 |
+
tokenizer = CLIPTokenizer.from_pretrained(clip_id)
|
| 318 |
+
text_encoder = CLIPTextModelWithProjection.from_pretrained(clip_id).to(device)
|
| 319 |
+
image_processor = CLIPImageProcessor.from_pretrained(clip_id)
|
| 320 |
+
image_encoder = CLIPVisionModelWithProjection.from_pretrained(clip_id).to(device)
|
| 321 |
+
```
|
| 322 |
+
|
| 323 |
+
주목할 점은 특정한 CLIP 체크포인트인 `openai/clip-vit-large-patch14`를 사용하고 있다는 것입니다. 이는 Stable Diffusion 사전 훈련이 이 CLIP 변형체와 함께 수행되었기 때문입니다. 자세한 내용은 [문서](https://huggingface.co/docs/transformers/model_doc/clip)를 참조하세요.
|
| 324 |
+
|
| 325 |
+
다음으로, 방향성 유사도를 계산하기 위해 PyTorch의 `nn.Module`을 준비합니다:
|
| 326 |
+
|
| 327 |
+
```python
|
| 328 |
+
import torch.nn as nn
|
| 329 |
+
import torch.nn.functional as F
|
| 330 |
+
|
| 331 |
+
|
| 332 |
+
class DirectionalSimilarity(nn.Module):
|
| 333 |
+
def __init__(self, tokenizer, text_encoder, image_processor, image_encoder):
|
| 334 |
+
super().__init__()
|
| 335 |
+
self.tokenizer = tokenizer
|
| 336 |
+
self.text_encoder = text_encoder
|
| 337 |
+
self.image_processor = image_processor
|
| 338 |
+
self.image_encoder = image_encoder
|
| 339 |
+
|
| 340 |
+
def preprocess_image(self, image):
|
| 341 |
+
image = self.image_processor(image, return_tensors="pt")["pixel_values"]
|
| 342 |
+
return {"pixel_values": image.to(device)}
|
| 343 |
+
|
| 344 |
+
def tokenize_text(self, text):
|
| 345 |
+
inputs = self.tokenizer(
|
| 346 |
+
text,
|
| 347 |
+
max_length=self.tokenizer.model_max_length,
|
| 348 |
+
padding="max_length",
|
| 349 |
+
truncation=True,
|
| 350 |
+
return_tensors="pt",
|
| 351 |
+
)
|
| 352 |
+
return {"input_ids": inputs.input_ids.to(device)}
|
| 353 |
+
|
| 354 |
+
def encode_image(self, image):
|
| 355 |
+
preprocessed_image = self.preprocess_image(image)
|
| 356 |
+
image_features = self.image_encoder(**preprocessed_image).image_embeds
|
| 357 |
+
image_features = image_features / image_features.norm(dim=1, keepdim=True)
|
| 358 |
+
return image_features
|
| 359 |
+
|
| 360 |
+
def encode_text(self, text):
|
| 361 |
+
tokenized_text = self.tokenize_text(text)
|
| 362 |
+
text_features = self.text_encoder(**tokenized_text).text_embeds
|
| 363 |
+
text_features = text_features / text_features.norm(dim=1, keepdim=True)
|
| 364 |
+
return text_features
|
| 365 |
+
|
| 366 |
+
def compute_directional_similarity(self, img_feat_one, img_feat_two, text_feat_one, text_feat_two):
|
| 367 |
+
sim_direction = F.cosine_similarity(img_feat_two - img_feat_one, text_feat_two - text_feat_one)
|
| 368 |
+
return sim_direction
|
| 369 |
+
|
| 370 |
+
def forward(self, image_one, image_two, caption_one, caption_two):
|
| 371 |
+
img_feat_one = self.encode_image(image_one)
|
| 372 |
+
img_feat_two = self.encode_image(image_two)
|
| 373 |
+
text_feat_one = self.encode_text(caption_one)
|
| 374 |
+
text_feat_two = self.encode_text(caption_two)
|
| 375 |
+
directional_similarity = self.compute_directional_similarity(
|
| 376 |
+
img_feat_one, img_feat_two, text_feat_one, text_feat_two
|
| 377 |
+
)
|
| 378 |
+
return directional_similarity
|
| 379 |
+
```
|
| 380 |
+
|
| 381 |
+
이제 `DirectionalSimilarity`를 사용해 보겠습니다.
|
| 382 |
+
|
| 383 |
+
```python
|
| 384 |
+
dir_similarity = DirectionalSimilarity(tokenizer, text_encoder, image_processor, image_encoder)
|
| 385 |
+
scores = []
|
| 386 |
+
|
| 387 |
+
for i in range(len(input_images)):
|
| 388 |
+
original_image = input_images[i]
|
| 389 |
+
original_caption = original_captions[i]
|
| 390 |
+
edited_image = edited_images[i]
|
| 391 |
+
modified_caption = modified_captions[i]
|
| 392 |
+
|
| 393 |
+
similarity_score = dir_similarity(original_image, edited_image, original_caption, modified_caption)
|
| 394 |
+
scores.append(float(similarity_score.detach().cpu()))
|
| 395 |
+
|
| 396 |
+
print(f"CLIP directional similarity: {np.mean(scores)}")
|
| 397 |
+
# CLIP directional similarity: 0.0797976553440094
|
| 398 |
+
```
|
| 399 |
+
|
| 400 |
+
CLIP 점수와 마찬가지로, CLIP 방향 유사성이 높을수록 좋습니다.
|
| 401 |
+
|
| 402 |
+
`StableDiffusionInstructPix2PixPipeline`은 `image_guidance_scale`과 `guidance_scale`이라는 두 가지 인자를 노출시킵니다. 이 두 인자를 조정하여 최종 편집된 이미지의 품질을 제어할 수 있습니다. 이 두 인자의 영향을 실험해보고 방향 유사성에 미치는 영향을 확인해보기를 권장합니다.
|
| 403 |
+
|
| 404 |
+
이러한 메트릭의 개념을 확장하여 원본 이미지와 편집된 버전의 유사성을 측정할 수 있습니다. 이를 위해 `F.cosine_similarity(img_feat_two, img_feat_one)`을 사용할 수 있습니다. 이러한 종류의 편집에서는 이미지의 주요 의미가 최대한 보존되어야 합니다. 즉, 높은 유사성 점수를 얻어야 합니다.
|
| 405 |
+
|
| 406 |
+
[`StableDiffusionPix2PixZeroPipeline`](https://huggingface.co/docs/diffusers/main/en/api/pipelines/pix2pix_zero#diffusers.StableDiffusionPix2PixZeroPipeline)와 같은 유사한 파이프라인에도 이러한 메트릭을 사용할 수 있습니다.
|
| 407 |
+
|
| 408 |
+
<Tip>
|
| 409 |
+
|
| 410 |
+
CLIP 점수와 CLIP 방향 유사성 모두 CLIP 모델에 의존하기 때문에 평가가 편향될 수 있습니다
|
| 411 |
+
|
| 412 |
+
</Tip>
|
| 413 |
+
|
| 414 |
+
***IS, FID (나중에 설명할 예정), 또는 KID와 같은 메트릭을 확장하는 것은 어려울 수 있습니다***. 평가 중인 모델이 대규모 이미지 캡셔닝 데이터셋 (예: [LAION-5B 데이터셋](https://laion.ai/blog/laion-5b/))에서 사전 훈련되었을 때 이는 문제가 될 수 있습니다. 왜냐하면 이러한 메트릭의 기반에는 중간 이미지 특징을 추출하기 위해 ImageNet-1k 데이터셋에서 사전 훈련된 InceptionNet이 사용되기 때문입니다. Stable Diffusion의 사전 훈련 데이터셋은 InceptionNet의 사전 훈련 데이터셋과 겹치는 부분이 제한적일 수 있으므로 따라서 여기에는 좋은 후보가 아닙니다.
|
| 415 |
+
|
| 416 |
+
***위의 메트릭을 사용하면 클래스 조건이 있는 모델을 평가할 수 있습니다. 예를 들어, [DiT](https://huggingface.co/docs/diffusers/main/en/api/pipelines/dit). 이는 ImageNet-1k 클래스에 조건을 걸고 사전 훈련되었습니다.***
|
| 417 |
+
|
| 418 |
+
### 클래스 조건화 이미지 생성[[class-conditioned-image-generation]]
|
| 419 |
+
|
| 420 |
+
클래스 조건화 생성 모델은 일반적으로 [ImageNet-1k](https://huggingface.co/datasets/imagenet-1k)와 같은 클래스 레이블이 지정된 데이터셋에서 사전 훈련됩니다. 이러한 모델을 평가하는 인기있는 지표에는 Fréchet Inception Distance (FID), Kernel Inception Distance (KID) 및 Inception Score (IS)가 있습니다. 이 문서에서는 FID ([Heusel et al.](https://huggingface.co/papers/1706.08500))에 초점을 맞추고 있습니다. [`DiTPipeline`](https://huggingface.co/docs/diffusers/api/pipelines/dit)을 사용하여 FID를 계산하는 방법을 보여줍니다. 이는 내부적으로 [DiT 모델](https://huggingface.co/papers/2212.09748)을 사용합니다.
|
| 421 |
+
|
| 422 |
+
FID는 두 개의 이미지 데이터셋이 얼마나 유사한지를 측정하는 것을 목표로 합니다. [이 자료](https://mmgeneration.readthedocs.io/en/latest/quick_run.html#fid)에 따르면:
|
| 423 |
+
|
| 424 |
+
> Fréchet Inception Distance는 두 개의 이미지 데이터셋 간의 유사성을 측정하는 지표입니다. 시각적 품질에 대한 인간 판단과 잘 상관되는 것으로 나타났으며, 주로 생성적 적대 신경망의 샘플 품질을 평가하는 데 사용됩니다. FID는 Inception 네트워크의 특징 표현에 맞게 적합한 두 개의 가우시안 사이의 Fréchet 거리를 계산하여 구합니다.
|
| 425 |
+
|
| 426 |
+
이 두 개의 데이터셋은 실제 이미지 데이터셋과 가짜 이미지 데이터셋(우리의 경우 생성된 이미지)입니다. FID는 일반적으로 두 개의 큰 데이터셋으로 계산됩니다. 그러나 이 문서에서는 두 개의 미니 데이터셋으로 작업할 것입니다.
|
| 427 |
+
|
| 428 |
+
먼저 ImageNet-1k 훈련 세트에서 몇 개의 이미지를 다운로드해 봅시다:
|
| 429 |
+
|
| 430 |
+
```python
|
| 431 |
+
from zipfile import ZipFile
|
| 432 |
+
import requests
|
| 433 |
+
|
| 434 |
+
|
| 435 |
+
def download(url, local_filepath):
|
| 436 |
+
r = requests.get(url)
|
| 437 |
+
with open(local_filepath, "wb") as f:
|
| 438 |
+
f.write(r.content)
|
| 439 |
+
return local_filepath
|
| 440 |
+
|
| 441 |
+
dummy_dataset_url = "https://hf.co/datasets/sayakpaul/sample-datasets/resolve/main/sample-imagenet-images.zip"
|
| 442 |
+
local_filepath = download(dummy_dataset_url, dummy_dataset_url.split("/")[-1])
|
| 443 |
+
|
| 444 |
+
with ZipFile(local_filepath, "r") as zipper:
|
| 445 |
+
zipper.extractall(".")
|
| 446 |
+
```
|
| 447 |
+
|
| 448 |
+
```python
|
| 449 |
+
from PIL import Image
|
| 450 |
+
import os
|
| 451 |
+
|
| 452 |
+
dataset_path = "sample-imagenet-images"
|
| 453 |
+
image_paths = sorted([os.path.join(dataset_path, x) for x in os.listdir(dataset_path)])
|
| 454 |
+
|
| 455 |
+
real_images = [np.array(Image.open(path).convert("RGB")) for path in image_paths]
|
| 456 |
+
```
|
| 457 |
+
|
| 458 |
+
다음은 ImageNet-1k classes의 이미지 10개입니다 : "cassette_player", "chain_saw" (x2), "church", "gas_pump" (x3), "parachute" (x2), 그리고 "tench".
|
| 459 |
+
|
| 460 |
+
<p align="center">
|
| 461 |
+
<img src="https://huggingface.co/datasets/diffusers/docs-images/resolve/main/evaluation_diffusion_models/real-images.png" alt="real-images"><br>
|
| 462 |
+
<em>Real images.</em>
|
| 463 |
+
</p>
|
| 464 |
+
|
| 465 |
+
이제 이미지가 로드되었으므로 이미지에 가벼운 전처리를 적용하여 FID 계산에 사용해 보겠습니다.
|
| 466 |
+
|
| 467 |
+
```python
|
| 468 |
+
from torchvision.transforms import functional as F
|
| 469 |
+
|
| 470 |
+
|
| 471 |
+
def preprocess_image(image):
|
| 472 |
+
image = torch.tensor(image).unsqueeze(0)
|
| 473 |
+
image = image.permute(0, 3, 1, 2) / 255.0
|
| 474 |
+
return F.center_crop(image, (256, 256))
|
| 475 |
+
|
| 476 |
+
real_images = torch.cat([preprocess_image(image) for image in real_images])
|
| 477 |
+
print(real_images.shape)
|
| 478 |
+
# torch.Size([10, 3, 256, 256])
|
| 479 |
+
```
|
| 480 |
+
|
| 481 |
+
이제 위에서 언급한 클래스에 따라 조건화 된 이미지를 생성하기 위해 [`DiTPipeline`](https://huggingface.co/docs/diffusers/api/pipelines/dit)를 로드합니다.
|
| 482 |
+
|
| 483 |
+
```python
|
| 484 |
+
from diffusers import DiTPipeline, DPMSolverMultistepScheduler
|
| 485 |
+
|
| 486 |
+
dit_pipeline = DiTPipeline.from_pretrained("facebook/DiT-XL-2-256", torch_dtype=torch.float16)
|
| 487 |
+
dit_pipeline.scheduler = DPMSolverMultistepScheduler.from_config(dit_pipeline.scheduler.config)
|
| 488 |
+
dit_pipeline = dit_pipeline.to("cuda")
|
| 489 |
+
|
| 490 |
+
words = [
|
| 491 |
+
"cassette player",
|
| 492 |
+
"chainsaw",
|
| 493 |
+
"chainsaw",
|
| 494 |
+
"church",
|
| 495 |
+
"gas pump",
|
| 496 |
+
"gas pump",
|
| 497 |
+
"gas pump",
|
| 498 |
+
"parachute",
|
| 499 |
+
"parachute",
|
| 500 |
+
"tench",
|
| 501 |
+
]
|
| 502 |
+
|
| 503 |
+
class_ids = dit_pipeline.get_label_ids(words)
|
| 504 |
+
output = dit_pipeline(class_labels=class_ids, generator=generator, output_type="np")
|
| 505 |
+
|
| 506 |
+
fake_images = output.images
|
| 507 |
+
fake_images = torch.tensor(fake_images)
|
| 508 |
+
fake_images = fake_images.permute(0, 3, 1, 2)
|
| 509 |
+
print(fake_images.shape)
|
| 510 |
+
# torch.Size([10, 3, 256, 256])
|
| 511 |
+
```
|
| 512 |
+
|
| 513 |
+
이제 [`torchmetrics`](https://torchmetrics.readthedocs.io/)를 사용하여 FID를 계산할 수 있습니다.
|
| 514 |
+
|
| 515 |
+
```python
|
| 516 |
+
from torchmetrics.image.fid import FrechetInceptionDistance
|
| 517 |
+
|
| 518 |
+
fid = FrechetInceptionDistance(normalize=True)
|
| 519 |
+
fid.update(real_images, real=True)
|
| 520 |
+
fid.update(fake_images, real=False)
|
| 521 |
+
|
| 522 |
+
print(f"FID: {float(fid.compute())}")
|
| 523 |
+
# FID: 177.7147216796875
|
| 524 |
+
```
|
| 525 |
+
|
| 526 |
+
FID는 낮을수록 좋습니다. 여러 가지 요소가 FID에 영향을 줄 수 있습니다:
|
| 527 |
+
|
| 528 |
+
- 이미지의 수 (실제 이미지와 가짜 이미지 모두)
|
| 529 |
+
- diffusion 과정에서 발생하는 무작위성
|
| 530 |
+
- diffusion 과정에서의 추론 단계 수
|
| 531 |
+
- diffusion 과정에서 사용되는 스케줄러
|
| 532 |
+
|
| 533 |
+
마지막 두 가지 요소에 대해서는, 다른 시드와 추론 단계에서 평가를 실행하고 평균 결과를 보고하는 것은 좋은 실천 방법입니다
|
| 534 |
+
|
| 535 |
+
<Tip warning={true}>
|
| 536 |
+
|
| 537 |
+
FID 결과는 많은 요소에 의존하기 때문에 취약할 수 있습니다:
|
| 538 |
+
|
| 539 |
+
* 계산 중 사용되는 특정 Inception 모델.
|
| 540 |
+
* 계산의 구현 정확도.
|
| 541 |
+
* 이미지 형식 (PNG 또는 JPG에서 시작하는 경우가 다릅니다).
|
| 542 |
+
|
| 543 |
+
이러한 사항을 염두에 두면, FID는 유사한 실행을 비교할 때 가장 유용하지만, 저자가 FID 측정 코드를 주의 깊게 공개하지 않는 한 논문 결과를 재현하기는 어렵습니다.
|
| 544 |
+
|
| 545 |
+
이러한 사항은 KID 및 IS와 같은 다른 관련 메트릭에도 적용됩니다.
|
| 546 |
+
|
| 547 |
+
</Tip>
|
| 548 |
+
|
| 549 |
+
마지막 단계로, `fake_images`를 시각적으로 검사해 봅시다.
|
| 550 |
+
|
| 551 |
+
<p align="center">
|
| 552 |
+
<img src="https://huggingface.co/datasets/diffusers/docs-images/resolve/main/evaluation_diffusion_models/fake-images.png" alt="fake-images"><br>
|
| 553 |
+
<em>Fake images.</em>
|
| 554 |
+
</p>
|
tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/conceptual/philosophy.md
ADDED
|
@@ -0,0 +1,103 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2024 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# 철학 [[philosophy]]
|
| 14 |
+
|
| 15 |
+
🧨 Diffusers는 다양한 모달리티에서 **최신의** 사전 훈련된 diffusion 모델을 제공합니다.
|
| 16 |
+
그 목적은 추론과 훈련을 위한 **모듈식 툴박스**로 사용되는 것입니다.
|
| 17 |
+
|
| 18 |
+
저희는 시간이 지나도 변치 않는 라이브러리를 구축하는 것을 목표로 하기에 API 설계를 매우 중요하게 생각합니다.
|
| 19 |
+
|
| 20 |
+
간단히 말해서, Diffusers는 PyTorch를 자연스럽게 확장할 수 있도록 만들어졌습니다. 따라서 대부분의 설계 선택은 [PyTorch의 설계 원칙](https://pytorch.org/docs/stable/community/design.html#pytorch-design-philosophy)에 기반합니다. 이제 가장 중요한 것들을 살펴보겠습니다:
|
| 21 |
+
|
| 22 |
+
## 성능보다는 사용성을 [[usability-over-performance]]
|
| 23 |
+
|
| 24 |
+
- Diffusers는 다양한 성능 향상 기능이 내장되어 있지만 (자세한 내용은 [메모리와 속도](https://huggingface.co/docs/diffusers/optimization/fp16) 참조), 모델은 항상 가장 높은 정밀도와 최소한의 최적화로 로드됩니다. 따라서 사용자가 별도로 정의하지 않는 한 기본적으로 diffusion 파이프라인은 항상 float32 정밀도로 CPU에 인스턴스화됩니다. 이는 다양한 플랫폼과 가속기에서의 사용성을 보장하며, 라이브러리를 실행하기 위해 복잡한 설치가 필요하지 않다는 것을 의미합니다.
|
| 25 |
+
- Diffusers는 **가벼운** 패키지를 지향하기 때문에 필수 종속성은 거의 없지만 성능을 향상시킬 수 있는 많은 선택적 종속성이 있습니다 (`accelerate`, `safetensors`, `onnx` 등). 저희는 라이브러리를 가능한 한 가볍게 유지하여 다른 패키지에 대한 종속성 걱정이 없도록 노력하고 있습니다.
|
| 26 |
+
- Diffusers는 간결하고 이해하기 쉬운 코드를 선호합니다. 이는 람다 함수나 고급 PyTorch 연산자와 같은 압축된 코드 구문을 자주 사용하지 않는 것을 의미합니다.
|
| 27 |
+
|
| 28 |
+
## 쉬움보다는 간단함을 [[simple-over-easy]]
|
| 29 |
+
|
| 30 |
+
PyTorch에서는 **명시적인 것이 암시적인 것보다 낫다**와 **단순한 것이 복잡한 것보다 낫다**라고 말합니다. 이 설계 철학은 라이브러리의 여러 부분에 반영되어 있습니다:
|
| 31 |
+
- [`DiffusionPipeline.to`](https://huggingface.co/docs/diffusers/main/en/api/diffusion_pipeline#diffusers.DiffusionPipeline.to)와 같은 메소드를 사용하여 사용자가 장치 관리를 할 수 있도록 PyTorch의 API를 따릅니다.
|
| 32 |
+
- 잘못된 입력을 조용히 수정하는 대신 간결한 오류 메시지를 발생시키는 것이 우선입니다. Diffusers는 라이브러리를 가능한 한 쉽게 사용할 수 있도록 하는 것보다 사용자를 가르치는 것을 목표로 합니다.
|
| 33 |
+
- 복잡한 모델과 스케줄러 로직이 내부에서 마법처럼 처리하는 대신 노출됩니다. 스케줄러/샘플러는 서로에게 최소한의 종속성을 가지고 분리되어 있습니다. 이로써 사용자는 언롤된 노이즈 제거 루프를 작성해야 합니다. 그러나 이 분리는 디버깅을 더 쉽게하고 노이즈 제거 과정을 조정하거나 diffusers 모델이나 스케줄러를 교체하는 데 사용자에게 더 많은 제어권을 제공합니다.
|
| 34 |
+
- diffusers 파이프라인의 따로 훈련된 구성 요소인 text encoder, unet 및 variational autoencoder는 각각 자체 모델 클래스를 갖습니다. 이로써 사용자는 서로 다른 모델의 구성 요소 간의 상호 작용을 처리해야 하며, 직렬화 형식은 모델 구성 요소를 다른 파일로 분리합니다. 그러나 이는 디버깅과 커스터마이징을 더 쉽게합니다. DreamBooth나 Textual Inversion 훈련은 Diffusers의 'diffusion 파이프라인의 단일 구성 요소들을 분리할 수 있는 능력' 덕분에 매우 간단합니다.
|
| 35 |
+
|
| 36 |
+
## 추상화보다는 수정 가능하고 기여하기 쉬움을 [[tweakable-contributor-friendly-over-abstraction]]
|
| 37 |
+
|
| 38 |
+
라이브러리의 대부분에 대해 Diffusers는 [Transformers 라이브러리](https://github.com/huggingface/transformers)의 중요한 설계 원칙을 채택합니다, 바로 성급한 추상화보다는 copy-pasted 코드를 선호한다는 것입니다. 이 설계 원칙은 [Don't repeat yourself (DRY)](https://en.wikipedia.org/wiki/Don%27t_repeat_yourself)와 같은 인기 있는 설계 원칙과는 대조적으로 매우 의견이 분분한데요.
|
| 39 |
+
간단히 말해서, Transformers가 모델링 파일에 대해 수행하는 것처럼, Diffusers는 매우 낮은 수준의 추상화와 매우 독립적인 코드를 유지하는 것을 선호합니다. 함수, 긴 코드 블록, 심지어 클래스도 여러 파일에 복사할 수 있으며, 이는 처음에는 라이브러리를 유지할 수 없게 만드는 나쁜, 서투른 설계 선택으로 보일 수 있습니다. 하지만 이러한 설계는 매우 성공적이며, 커뮤니티 기반의 오픈 소스 기계 학습 라이브러리에 매우 적합합니다. 그 이유는 다음과 같습니다:
|
| 40 |
+
- 기계 학습은 패러다임, 모델 아키텍처 및 알고리즘이 빠르게 변화하는 매우 빠르게 움직이는 분야이기 때문에 오랜 기간 지속되는 코드 추상화를 정의하기가 매우 어렵습니다.
|
| 41 |
+
- 기계 학습 전문가들은 아이디어와 연구를 위해 기존 코드를 빠르게 조정할 수 있어야 하므로, 많은 추상화보다는 독립적인 코드를 선호합니다.
|
| 42 |
+
- 오픈 소스 라이브러리는 커뮤니티 기여에 의존하므로, 기여하기 쉬운 라이브러리를 구축해야 합니다. 코드가 추상화되면 의존성이 많아지고 읽기 어렵고 기여하기 어려워집니다. 기여자들은 중요한 기능을 망가뜨릴까 두려워하여 매우 추상화된 라이브러리에 기여하지 않게 됩니다. 라이브러리에 기여하는 것이 다른 기본 코드를 망가뜨릴 수 없다면, 잠재적인 새로운 기여자에게 더욱 환영받을 수 있을 뿐만 아니라 여러 부분에 대해 병렬적으로 검토하고 기여하기가 더 쉬워집니다.
|
| 43 |
+
|
| 44 |
+
Hugging Face에서는 이 설계를 **단일 파일 정책**이라고 부르며, 특정 클래스의 대부분의 코드가 단일하고 독립적인 파일에 작성되어야 한다는 의미입니다. 철학에 대해 자세히 알아보려면 [이 블로그 글](https://huggingface.co/blog/transformers-design-philosophy)을 참조할 수 있습니다.
|
| 45 |
+
|
| 46 |
+
Diffusers에서는 이러한 철학을 파이프라인과 스케줄러에 모두 따르지만, diffusion 모델에 대해서는 일부만 따릅니다. 일부만 따르는 이유는 Diffusion 파이프라인인 [DDPM](https://huggingface.co/docs/diffusers/api/pipelines/ddpm), [Stable Diffusion](https://huggingface.co/docs/diffusers/api/pipelines/stable_diffusion/overview#stable-diffusion-pipelines), [unCLIP (DALL·E 2)](https://huggingface.co/docs/diffusers/api/pipelines/unclip) 및 [Imagen](https://imagen.research.google/) 등 대부분의 diffusion 파이프라인은 동일한 diffusion 모델인 [UNet](https://huggingface.co/docs/diffusers/api/models/unet2d-cond)에 의존하기 때문입니다.
|
| 47 |
+
|
| 48 |
+
좋아요, 이제 🧨 Diffusers가 설계된 방식을 대략적으로 이해했을 것입니다 🤗.
|
| 49 |
+
우리는 이러한 설계 원칙을 일관되게 라이브러리 전체에 적용하려고 노력하고 있습니다. 그럼에도 불구하고 철학에 대한 일부 예외 사항이나 불행한 설계 선택이 있을 수 있습니다. 디자인에 대한 피드백이 있다면 [GitHub에서 직접](https://github.com/huggingface/diffusers/issues/new?assignees=&labels=&template=feedback.md&title=) 알려주시면 감사하겠습니다.
|
| 50 |
+
|
| 51 |
+
## 디자인 철학 자세히 알아보기 [[design-philosophy-in-details]]
|
| 52 |
+
|
| 53 |
+
이제 디자인 철학의 세부 사항을 좀 더 자세히 살펴보겠습니다. Diffusers는 주로 세 가지 주요 클래스로 구성됩니다: [파이프라인](https://github.com/huggingface/diffusers/tree/main/src/diffusers/pipelines), [모델](https://github.com/huggingface/diffusers/tree/main/src/diffusers/models), 그리고 [스케줄러](https://github.com/huggingface/diffusers/tree/main/src/diffusers/schedulers). 각 클래스에 대한 더 자세한 설계 결정 사항을 살펴보겠습니다.
|
| 54 |
+
|
| 55 |
+
### 파이프라인 [[pipelines]]
|
| 56 |
+
|
| 57 |
+
파이프라인은 사용하기 쉽도록 설계되었으며 (따라서 [*쉬움보다는 간단함을*](#쉬움보다는-간단함을)을 100% 따르지는 않음), feature-complete하지 않으며, 추론을 위한 [모델](#모델)과 [스케줄러](#스케줄러)를 사용하는 방법의 예시로 간주될 수 있습니다.
|
| 58 |
+
|
| 59 |
+
다음과 같은 설계 원칙을 따릅니다:
|
| 60 |
+
- 파이프라인은 단일 파일 정책을 따릅니다. 모든 파이프라인은 src/diffusers/pipelines의 개별 디렉토리에 있습니다. 하나의 파이프라인 폴더는 하나의 diffusion 논문/프로젝트/릴리스에 해당합니다. 여러 파이프라인 파일은 하나의 파이프라인 폴더에 모을 수 있습니다. 예를 들어 [`src/diffusers/pipelines/stable-diffusion`](https://github.com/huggingface/diffusers/tree/main/src/diffusers/pipelines/stable_diffusion)에서 그렇게 하고 있습니다. 파이프라인이 유사한 기능을 공유하는 경우, [# Copied from mechanism](https://github.com/huggingface/diffusers/blob/125d783076e5bd9785beb05367a2d2566843a271/src/diffusers/pipelines/stable_diffusion/pipeline_stable_diffusion_img2img.py#L251)을 사용할 수 있습니다.
|
| 61 |
+
- 파이프라인은 모두 [`DiffusionPipeline`]을 상속합니다.
|
| 62 |
+
- 각 파이프라인은 서로 다른 모델 및 스케줄러 구성 요소로 구성되어 있으며, 이는 [`model_index.json` 파일](https://huggingface.co/stable-diffusion-v1-5/stable-diffusion-v1-5/blob/main/model_index.json)에 문서화되어 있으며, 파이프라인의 속성 이름과 동일한 이름으로 액세스할 수 있으며, [`DiffusionPipeline.components`](https://huggingface.co/docs/diffusers/main/en/api/diffusion_pipeline#diffusers.DiffusionPipeline.components) 함수를 통해 파이프라인 간에 공유할 수 있습니다.
|
| 63 |
+
- 각 파이프라인은 [`DiffusionPipeline.from_pretrained`](https://huggingface.co/docs/diffusers/main/en/api/diffusion_pipeline#diffusers.DiffusionPipeline.from_pretrained) 함수를 통해 로드할 수 있어야 합니다.
|
| 64 |
+
- 파이프라인은 추론에**만** 사용되어야 합니다.
|
| 65 |
+
- 파이프라인은 매우 가독성이 좋고, 이해하기 쉽고, 쉽게 조정할 수 있도록 설계되어야 합니다.
|
| 66 |
+
- 파이프라인은 서로 상호작용하고, 상위 수준 API에 쉽게 통합할 수 있도록 설계되어야 합니다.
|
| 67 |
+
- 파이프라인은 사용자 인터페이스가 feature-complete하지 않게 하는 것을 목표로 합니다. future-complete한 사용자 인터페이스를 원한다면 [InvokeAI](https://github.com/invoke-ai/InvokeAI), [Diffuzers](https://github.com/abhishekkrthakur/diffuzers), [lama-cleaner](https://github.com/Sanster/lama-cleaner)를 참조해야 합니다.
|
| 68 |
+
- 모든 파이프라인은 오로지 `__call__` 메소드를 통해 실행할 수 있어야 합니다. `__call__` 인자의 이름은 모든 파이프라인에서 공유되어야 합니다.
|
| 69 |
+
- 파이프라인은 해결하고자 하는 작업의 이름으로 지정되어야 합니다.
|
| 70 |
+
- 대부분의 경우에 새로운 diffusion 파이프라인은 새로운 파이프라인 폴더/파일에 구현되어야 합니다.
|
| 71 |
+
|
| 72 |
+
### 모델 [[models]]
|
| 73 |
+
|
| 74 |
+
모델은 [PyTorch의 Module 클래스](https://pytorch.org/docs/stable/generated/torch.nn.Module.html)의 자연스러운 확장이 되도록, 구성 가능한 툴박스로 설계되었습니다. 그리고 모델은 **단일 파일 정책**을 일부만 따릅니다.
|
| 75 |
+
|
| 76 |
+
다음과 같은 설계 원칙을 따릅니다:
|
| 77 |
+
- 모델은 **모델 아키텍처 유형**에 해당합니다. 예를 들어 [`UNet2DConditionModel`] 클래스는 2D 이미지 입력을 기대하고 일부 context에 의존하는 모든 UNet 변형들에 사용됩니다.
|
| 78 |
+
- 모든 모델은 [`src/diffusers/models`](https://github.com/huggingface/diffusers/tree/main/src/diffusers/models)에서 찾을 수 있으며, 각 모델 아키텍처는 해당 파일에 정의되어야 합니다. 예를 들어 [`unet_2d_condition.py`](https://github.com/huggingface/diffusers/blob/main/src/diffusers/models/unet_2d_condition.py), [`transformer_2d.py`](https://github.com/huggingface/diffusers/blob/main/src/diffusers/models/transformer_2d.py) 등이 있습니다.
|
| 79 |
+
- 모델은 **단일 파일 정책**을 따르지 않으며, [`attention.py`](https://github.com/huggingface/diffusers/blob/main/src/diffusers/models/attention.py), [`resnet.py`](https://github.com/huggingface/diffusers/blob/main/src/diffusers/models/resnet.py), [`embeddings.py`](https://github.com/huggingface/diffusers/blob/main/src/diffusers/models/embeddings.py) 등과 같은 작은 모델 구성 요소를 사용해야 합니다. **참고**: 이는 Transformers의 모델링 파일과는 대조적으로 모델이 실제로 단일 파일 정책을 따르지 않음을 보여줍니다.
|
| 80 |
+
- 모델은 PyTorch의 `Module` 클래스와 마찬가지로 복잡성을 노출하고 명확한 오류 메시지를 제공해야 합니다.
|
| 81 |
+
- 모든 모델은 `ModelMixin`과 `ConfigMixin`을 상속합니다.
|
| 82 |
+
- 모델은 주요 코드 변경이 필요하지 않고, 역호환성을 유지하며, 메모리 또는 컴퓨팅과 관련한 중요한 이득을 제공할 때 성능을 위해 최적화할 수 있습니다.
|
| 83 |
+
- 모델은 기본적으로 가장 높은 정밀도와 가장 낮은 성능 설정을 가져야 합니다.
|
| 84 |
+
- Diffusers에 이미 있는 모델 아키텍처로 분류할 수 있는 새로운 모델 체크포인트를 통합할 때는 기존 모델 아키텍처를 새로운 체크포인트와 호환되도록 수정해야 합니다. 새로운 파일을 만들어야 하는 경우는 모델 아키텍처가 근본적으로 다른 경우에만 해당합니다.
|
| 85 |
+
- 모델은 미래의 변경 사항을 쉽게 확장할 수 있도록 설계되어야 합니다. 이는 공개 함수 인수들과 구성 인수들을 제한하고,미래의 변경 사항을 "예상"하는 것을 통해 달성할 수 있습니다. 예를 들어, 불리언 `is_..._type` 인수보다는 새로운 미래 유형에 쉽게 확장할 수 있는 문자열 "...type" 인수를 추가하는 것이 일반적으로 더 좋습니다. 새로운 모델 체크포인트가 작동하도록 하기 위해 기존 아키텍처에 최소한의 변경만을 가해야 합���다.
|
| 86 |
+
- 모델 디자인은 코드의 가독성과 간결성을 유지하는 것과 많은 모델 체크포인트를 지원하는 것 사이의 어려운 균형 조절입니다. 모델링 코드의 대부분은 새로운 모델 체크포인트를 위해 클래스를 수정하는 것이 좋지만, [UNet 블록](https://github.com/huggingface/diffusers/blob/main/src/diffusers/models/unet_2d_blocks.py) 및 [Attention 프로세서](https://github.com/huggingface/diffusers/blob/main/src/diffusers/models/attention_processor.py)와 같이 코드를 장기적으로 간결하고 읽기 쉽게 유지하기 위해 새로운 클래스를 추가하는 예외도 있습니다.
|
| 87 |
+
|
| 88 |
+
### 스케줄러 [[schedulers]]
|
| 89 |
+
|
| 90 |
+
스케줄러는 추론을 위한 노이즈 제거 과정을 안내하고 훈련을 위한 노이즈 스케줄을 정의하는 역할을 합니다. 스케줄러는 개별 클래스로 설계되어 있으며, 로드 가능한 구성 파일과 **단일 파일 정책**을 엄격히 따릅니다.
|
| 91 |
+
|
| 92 |
+
다음과 같은 설계 원칙을 따릅니다:
|
| 93 |
+
- 모든 스케줄러는 [`src/diffusers/schedulers`](https://github.com/huggingface/diffusers/tree/main/src/diffusers/schedulers)에서 찾을 수 있습니다.
|
| 94 |
+
- 스케줄러는 큰 유틸리티 파일에서 가져오지 **않아야** 하며, 자체 포함성을 유지해야 합니다.
|
| 95 |
+
- 하나의 스케줄러 Python 파일은 하나의 스케줄러 알고리즘(논문에서 정의된 것과 같은)에 해당합니다.
|
| 96 |
+
- 스케줄러가 유사한 기능을 공유하는 경우, `# Copied from` 메커니즘을 사용할 수 있습니다.
|
| 97 |
+
- 모든 스케줄러는 `SchedulerMixin`과 `ConfigMixin`을 상속합니다.
|
| 98 |
+
- [`ConfigMixin.from_config`](https://huggingface.co/docs/diffusers/main/en/api/configuration#diffusers.ConfigMixin.from_config) 메소드를 사용하여 스케줄러를 쉽게 교체할 수 있습니다. 자세한 내용은 [여기](../using-diffusers/schedulers.md)에서 설명합니다.
|
| 99 |
+
- 모든 스케줄러는 `set_num_inference_steps`와 `step` 함수를 가져야 합니다. `set_num_inference_steps(...)`는 각 노이즈 제거 과정(즉, `step(...)`이 호출되기 전) 이전에 호출되어야 합니다.
|
| 100 |
+
- 각 스케줄러는 모델이 호출될 타임스텝의 배열인 `timesteps` 속성을 통해 루프를 돌 수 있는 타임스텝을 노출합니다.
|
| 101 |
+
- `step(...)` 함수는 예측된 모델 출력과 "현재" 샘플(x_t)을 입력으로 받고, "이전" 약간 더 노이즈가 제거된 샘플(x_t-1)을 반환합니다.
|
| 102 |
+
- 노이즈 제거 스케줄러의 복잡성을 고려하여, `step` 함수는 모든 복잡성을 노출하지 않으며, "블랙 박스"일 수 있습니다.
|
| 103 |
+
- 거의 모든 경우에 새로운 스케줄러는 새로운 스케줄링 파일에 구현되어야 합니다.
|
tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/in_translation.md
ADDED
|
@@ -0,0 +1,16 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2024 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# 번역중
|
| 14 |
+
|
| 15 |
+
열심히 번역을 진행중입니다. 조금만 기다려주세요.
|
| 16 |
+
감사합니다!
|
tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/index.md
ADDED
|
@@ -0,0 +1,49 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2024 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
<p align="center">
|
| 14 |
+
<br>
|
| 15 |
+
<img src="https://raw.githubusercontent.com/huggingface/diffusers/77aadfee6a891ab9fcfb780f87c693f7a5beeb8e/docs/source/imgs/diffusers_library.jpg" width="400"/>
|
| 16 |
+
<br>
|
| 17 |
+
</p>
|
| 18 |
+
|
| 19 |
+
|
| 20 |
+
# Diffusers
|
| 21 |
+
|
| 22 |
+
🤗 Diffusers는 이미지, 오디오, 심지어 분자의 3D 구조를 생성하기 위한 최첨단 사전 훈련된 diffusion 모델을 위한 라이브러리입니다. 간단한 추론 솔루션을 찾고 있든, 자체 diffusion 모델을 훈련하고 싶든, 🤗 Diffusers는 두 가지 모두를 지원하는 모듈식 툴박스입니다. 저희 라이브러리는 [성능보다 사용성](conceptual/philosophy#usability-over-performance), [간편함보다 단순함](conceptual/philosophy#simple-over-easy), 그리고 [추상화보다 사용자 지정 가능성](conceptual/philosophy#tweakable-contributorfriendly-over-abstraction)에 중점을 두고 설계되었습니다.
|
| 23 |
+
|
| 24 |
+
이 라이브러리에는 세 가지 주요 구성 요소가 있습니다:
|
| 25 |
+
|
| 26 |
+
- 몇 줄의 코드만으로 추론할 수 있는 최첨단 [diffusion 파이프라인](api/pipelines/overview).
|
| 27 |
+
- 생성 속도와 품질 간의 균형을 맞추기 위해 상호교환적으로 사용할 수 있는 [노이즈 스케줄러](api/schedulers/overview).
|
| 28 |
+
- 빌딩 블록으로 사용할 수 있고 스케줄러와 결합하여 자체적인 end-to-end diffusion 시스템을 만들 수 있는 사전 학습된 [모델](api/models).
|
| 29 |
+
|
| 30 |
+
<div class="mt-10">
|
| 31 |
+
<div class="w-full flex flex-col space-y-4 md:space-y-0 md:grid md:grid-cols-2 md:gap-y-4 md:gap-x-5">
|
| 32 |
+
<a class="!no-underline border dark:border-gray-700 p-5 rounded-lg shadow hover:shadow-lg" href="./tutorials/tutorial_overview"
|
| 33 |
+
><div class="w-full text-center bg-gradient-to-br from-blue-400 to-blue-500 rounded-lg py-1.5 font-semibold mb-5 text-white text-lg leading-relaxed">Tutorials</div>
|
| 34 |
+
<p class="text-gray-700">결과물을 생성하고, 나만의 diffusion 시스템을 구축하고, 확산 모델을 훈련하는 데 필요한 기본 기술을 배워보세요. 🤗 Diffusers를 처음 사용하는 경우 여기에서 시작하는 것이 좋습니다!</p>
|
| 35 |
+
</a>
|
| 36 |
+
<a class="!no-underline border dark:border-gray-700 p-5 rounded-lg shadow hover:shadow-lg" href="./using-diffusers/loading_overview"
|
| 37 |
+
><div class="w-full text-center bg-gradient-to-br from-indigo-400 to-indigo-500 rounded-lg py-1.5 font-semibold mb-5 text-white text-lg leading-relaxed">How-to guides</div>
|
| 38 |
+
<p class="text-gray-700">파이프라인, 모델, 스케줄러를 로드하는 데 도움이 되는 실용적인 가이드입니다. 또한 특정 작업에 파이프라인을 사용하고, 출력 생성 방식을 제어하고, 추론 속도에 맞게 최적화하고, 다양한 학습 기법을 사용하는 방법도 배울 수 있습니다.</p>
|
| 39 |
+
</a>
|
| 40 |
+
<a class="!no-underline border dark:border-gray-700 p-5 rounded-lg shadow hover:shadow-lg" href="./conceptual/philosophy"
|
| 41 |
+
><div class="w-full text-center bg-gradient-to-br from-pink-400 to-pink-500 rounded-lg py-1.5 font-semibold mb-5 text-white text-lg leading-relaxed">Conceptual guides</div>
|
| 42 |
+
<p class="text-gray-700">라이브러리가 왜 이런 방식으로 설계되었는지 이해하고, 라이브러리 이용에 대한 윤리적 가이드라인과 안전 구현에 대해 자세히 알아보세요.</p>
|
| 43 |
+
</a>
|
| 44 |
+
<a class="!no-underline border dark:border-gray-700 p-5 rounded-lg shadow hover:shadow-lg" href="./api/models"
|
| 45 |
+
><div class="w-full text-center bg-gradient-to-br from-purple-400 to-purple-500 rounded-lg py-1.5 font-semibold mb-5 text-white text-lg leading-relaxed">Reference</div>
|
| 46 |
+
<p class="text-gray-700">🤗 Diffusers 클래스 및 메서드의 작동 방식에 대한 기술 설명.</p>
|
| 47 |
+
</a>
|
| 48 |
+
</div>
|
| 49 |
+
</div>
|
tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/installation.md
ADDED
|
@@ -0,0 +1,142 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2024 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# 설치
|
| 14 |
+
|
| 15 |
+
사용하시는 라이브러리에 맞는 🤗 Diffusers를 설치하세요.
|
| 16 |
+
|
| 17 |
+
🤗 Diffusers는 Python 3.8+, PyTorch 1.7.0+ 및 flax에서 테스트되었습니다. 사용중인 딥러닝 라이브러리에 대한 아래의 설치 안내를 따르세요.
|
| 18 |
+
|
| 19 |
+
- [PyTorch 설치 안내](https://pytorch.org/get-started/locally/)
|
| 20 |
+
- [Flax 설치 안내](https://flax.readthedocs.io/en/latest/)
|
| 21 |
+
|
| 22 |
+
## pip를 이용한 설치
|
| 23 |
+
|
| 24 |
+
[가상 환경](https://docs.python.org/3/library/venv.html)에 🤗 Diffusers를 설치해야 합니다.
|
| 25 |
+
Python 가상 환경에 익숙하지 않은 경우 [가상환경 pip 설치 가이드](https://packaging.python.org/guides/installing-using-pip-and-virtual-environments/)를 살펴보세요.
|
| 26 |
+
가상 환경을 사용하면 서로 다른 프로젝트를 더 쉽게 관리하고, 종속성간의 호환성 문제를 피할 수 있습니다.
|
| 27 |
+
|
| 28 |
+
프로젝트 디렉토리에 가상 환경을 생성하는 것으로 시작하세요:
|
| 29 |
+
|
| 30 |
+
```bash
|
| 31 |
+
python -m venv .env
|
| 32 |
+
```
|
| 33 |
+
|
| 34 |
+
그리고 가상 환경을 활성화합니다:
|
| 35 |
+
|
| 36 |
+
```bash
|
| 37 |
+
source .env/bin/activate
|
| 38 |
+
```
|
| 39 |
+
|
| 40 |
+
이제 다음의 명령어로 🤗 Diffusers를 설치할 준비가 되었습니다:
|
| 41 |
+
|
| 42 |
+
**PyTorch의 경우**
|
| 43 |
+
|
| 44 |
+
```bash
|
| 45 |
+
pip install diffusers["torch"]
|
| 46 |
+
```
|
| 47 |
+
|
| 48 |
+
**Flax의 경우**
|
| 49 |
+
|
| 50 |
+
```bash
|
| 51 |
+
pip install diffusers["flax"]
|
| 52 |
+
```
|
| 53 |
+
|
| 54 |
+
## 소스로부터 설치
|
| 55 |
+
|
| 56 |
+
소스에서 `diffusers`를 설치하기 전에, `torch` 및 `accelerate`이 설치되어 있는지 확인하세요.
|
| 57 |
+
|
| 58 |
+
`torch` 설치에 대해서는 [torch docs](https://pytorch.org/get-started/locally/#start-locally)를 참고하세요.
|
| 59 |
+
|
| 60 |
+
다음과 같이 `accelerate`을 설치하세요.
|
| 61 |
+
|
| 62 |
+
```bash
|
| 63 |
+
pip install accelerate
|
| 64 |
+
```
|
| 65 |
+
|
| 66 |
+
다음 명령어를 사용하여 소스에서 🤗 Diffusers를 설치하세요:
|
| 67 |
+
|
| 68 |
+
```bash
|
| 69 |
+
pip install git+https://github.com/huggingface/diffusers
|
| 70 |
+
```
|
| 71 |
+
|
| 72 |
+
이 명령어는 최신 `stable` 버전이 아닌 최첨단 `main` 버전을 설치합니다.
|
| 73 |
+
`main` 버전은 최신 개발 정보를 최신 상태로 유지하는 데 유용합니다.
|
| 74 |
+
예를 들어 마지막 공식 릴리즈 이후 버그가 수정되었지만, 새 릴리즈가 아직 출시되지 않은 경우입니다.
|
| 75 |
+
그러나 이는 `main` 버전이 항상 안정적이지 않을 수 있음을 의미합니다.
|
| 76 |
+
우리는 `main` 버전이 지속적으로 작동하도록 노력하고 있으며, 대부분의 문제는 보통 몇 시간 또는 하루 안에 해결됩니다.
|
| 77 |
+
문제가 발생하면 더 빨리 해결할 수 있도록 [Issue](https://github.com/huggingface/transformers/issues)를 열어주세요!
|
| 78 |
+
|
| 79 |
+
|
| 80 |
+
## 편집가능한 설치
|
| 81 |
+
|
| 82 |
+
다음을 수행하려면 편집가능한 설치가 필요합니다:
|
| 83 |
+
|
| 84 |
+
* 소스 코드의 `main` 버전을 사용
|
| 85 |
+
* 🤗 Diffusers에 기여 (코드의 변경 사항을 테스트하기 위해 필요)
|
| 86 |
+
|
| 87 |
+
저장소를 복제하고 다음 명령어를 사용하여 🤗 Diffusers를 설치합니다:
|
| 88 |
+
|
| 89 |
+
```bash
|
| 90 |
+
git clone https://github.com/huggingface/diffusers.git
|
| 91 |
+
cd diffusers
|
| 92 |
+
```
|
| 93 |
+
|
| 94 |
+
**PyTorch의 경우**
|
| 95 |
+
|
| 96 |
+
```sh
|
| 97 |
+
pip install -e ".[torch]"
|
| 98 |
+
```
|
| 99 |
+
|
| 100 |
+
**Flax의 경우**
|
| 101 |
+
|
| 102 |
+
```sh
|
| 103 |
+
pip install -e ".[flax]"
|
| 104 |
+
```
|
| 105 |
+
|
| 106 |
+
이러한 명령어들은 저장소를 복제한 폴더와 Python 라이브러리 경로를 연결합니다.
|
| 107 |
+
Python은 이제 일반 라이브러리 경로에 더하여 복제한 폴더 내부를 살펴봅니다.
|
| 108 |
+
예를들어 Python 패키지가 `~/anaconda3/envs/main/lib/python3.10/site-packages/`에 설치되어 있는 경우 Python은 복제한 폴더인 `~/diffusers/`도 검색합니다.
|
| 109 |
+
|
| 110 |
+
<Tip warning={true}>
|
| 111 |
+
|
| 112 |
+
라이브러리를 계속 사용하려면 `diffusers` 폴더를 유지해야 합니다.
|
| 113 |
+
|
| 114 |
+
</Tip>
|
| 115 |
+
|
| 116 |
+
이제 다음 명령어를 사용하여 최신 버전의 🤗 Diffusers로 쉽게 업데이트할 수 있습니다:
|
| 117 |
+
|
| 118 |
+
```bash
|
| 119 |
+
cd ~/diffusers/
|
| 120 |
+
git pull
|
| 121 |
+
```
|
| 122 |
+
|
| 123 |
+
이렇게 하면, 다음에 실행할 때 Python 환경이 🤗 Diffusers의 `main` 버전을 찾게 됩니다.
|
| 124 |
+
|
| 125 |
+
## 텔레메트리 로깅에 대한 알림
|
| 126 |
+
|
| 127 |
+
우리 라이브러리는 `from_pretrained()` 요청 중에 텔레메트리 정보를 원격으로 수집합니다.
|
| 128 |
+
이 데이터에는 Diffusers 및 PyTorch/Flax의 버전, 요청된 모델 또는 파이프라인 클래스, 그리고 허브에서 호스팅되는 경우 사전학습된 체크포인트에 대한 경로를 포함합니다.
|
| 129 |
+
이 사용 데이터는 문제를 디버깅하고 새로운 기능의 우선순위를 지정하는데 도움이 됩니다.
|
| 130 |
+
텔레메트리는 HuggingFace 허브에서 모델과 ��이프라인을 불러올 때만 전송되며, 로컬 사용 중에는 수집되지 않습니다.
|
| 131 |
+
|
| 132 |
+
우리는 추가 정보를 공유하지 않기를 원하는 사람이 있다는 것을 이해하고 개인 정보를 존중하므로, 터미널에서 `DISABLE_TELEMETRY` 환경 변수를 설정하여 텔레메트리 수집을 비활성화할 수 있습니다.
|
| 133 |
+
|
| 134 |
+
Linux/MacOS에서:
|
| 135 |
+
```bash
|
| 136 |
+
export DISABLE_TELEMETRY=YES
|
| 137 |
+
```
|
| 138 |
+
|
| 139 |
+
Windows에서:
|
| 140 |
+
```bash
|
| 141 |
+
set DISABLE_TELEMETRY=YES
|
| 142 |
+
```
|
tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/optimization/coreml.md
ADDED
|
@@ -0,0 +1,168 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2024 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Core ML로 Stable Diffusion을 실행하는 방법
|
| 14 |
+
|
| 15 |
+
[Core ML](https://developer.apple.com/documentation/coreml)은 Apple 프레임워크에서 지원하는 모델 형식 및 머신 러닝 라이브러리입니다. macOS 또는 iOS/iPadOS 앱 내에서 Stable Diffusion 모델을 실행하는 데 관심이 있는 경우, 이 가이드에서는 기존 PyTorch 체크포인트를 Core ML 형식으로 변환하고 이를 Python 또는 Swift로 추론에 사용하는 방법을 설명합니다.
|
| 16 |
+
|
| 17 |
+
Core ML 모델은 Apple 기기에서 사용할 수 있는 모든 컴퓨팅 엔진들, 즉 CPU, GPU, Apple Neural Engine(또는 Apple Silicon Mac 및 최신 iPhone/iPad에서 사용할 수 있는 텐서 최적화 가속기인 ANE)을 활용할 수 있습니다. 모델과 실행 중인 기기에 따라 Core ML은 컴퓨팅 엔진도 혼합하여 사용할 수 있으므로, 예를 들어 모델의 일부가 CPU에서 실행되는 반면 다른 부분은 GPU에서 실행될 수 있습니다.
|
| 18 |
+
|
| 19 |
+
<Tip>
|
| 20 |
+
|
| 21 |
+
PyTorch에 내장된 `mps` 가속기를 사용하여 Apple Silicon Macs에서 `diffusers` Python 코드베이스를 실행할 수도 있습니다. 이 방법은 [mps 가이드]에 자세히 설명되어 있지만 네이티브 앱과 호환되지 않습니다.
|
| 22 |
+
|
| 23 |
+
</Tip>
|
| 24 |
+
|
| 25 |
+
## Stable Diffusion Core ML 체크포인트
|
| 26 |
+
|
| 27 |
+
Stable Diffusion 가중치(또는 체크포인트)는 PyTorch 형식으로 저장되기 때문에 네이티브 앱에서 사용하기 위해서는 Core ML 형식으로 변환해야 합니다.
|
| 28 |
+
|
| 29 |
+
다행히도 Apple 엔지니어들이 `diffusers`를 기반으로 한 [변환 툴](https://github.com/apple/ml-stable-diffusion#-converting-models-to-core-ml)을 개발하여 PyTorch 체크포인트를 Core ML로 변환할 수 있습니다.
|
| 30 |
+
|
| 31 |
+
모델을 변환하기 전에 잠시 시간을 내어 Hugging Face Hub를 살펴보세요. 관심 있는 모델이 이미 Core ML 형식으로 제공되고 있을 가능성이 높습니다:
|
| 32 |
+
|
| 33 |
+
- [Apple](https://huggingface.co/apple) organization에는 Stable Diffusion 버전 1.4, 1.5, 2.0 base 및 2.1 base가 포함되어 있습니다.
|
| 34 |
+
- [coreml](https://huggingface.co/coreml) organization에는 커스텀 DreamBooth가 적용되거나, 파인튜닝된 모델이 포함되어 있습니다.
|
| 35 |
+
- 이 [필터](https://huggingface.co/models?pipeline_tag=text-to-image&library=coreml&p=2&sort=likes)를 사용하여 사용 가능한 모든 Core ML 체크포인트들을 반환합니다.
|
| 36 |
+
|
| 37 |
+
원하는 모델을 찾을 수 없는 경우 Apple의 [모델을 Core ML로 변환하기](https://github.com/apple/ml-stable-diffusion#-converting-models-to-core-ml) 지침을 따르는 것이 좋습니다.
|
| 38 |
+
|
| 39 |
+
## 사용할 Core ML 변형(Variant) 선택하기
|
| 40 |
+
|
| 41 |
+
Stable Diffusion 모델은 다양한 목적에 따라 다른 Core ML 변형으로 변환할 수 있습니다:
|
| 42 |
+
|
| 43 |
+
- 사용되는 어텐션 블록 유형. 어텐션 연산은 이미지 표현의 여러 영역 간의 관계에 '주의를 기울이고' 이미지와 텍스트 표현이 어떻게 연관되어 있는지 이해하는 데 사용됩니다. 어텐션 연산은 컴퓨팅 및 메모리 집약적이므로 다양한 장치의 하드웨어 특성을 고려한 다양한 구현이 존재합니다. Core ML Stable Diffusion 모델의 경우 두 가지 주의 변형이 있습니다:
|
| 44 |
+
* `split_einsum` ([Apple에서 도입](https://machinelearning.apple.com/research/neural-engine-transformers)은 최신 iPhone, iPad 및 M 시리즈 컴퓨터에서 사용할 수 있는 ANE 장치에 최적화되어 있습니다.
|
| 45 |
+
* "원본" 어텐션(`diffusers`에 사용되는 기본 구현)는 CPU/GPU와만 호환되며 ANE와는 호환되지 않습니다. "원본" 어텐션을 사용하여 CPU + GPU에서 모델을 실행하는 것이 ANE보다 *더* 빠를 수 있습니다. 자세한 내용은 [이 성능 벤치마크](https://huggingface.co/blog/fast-mac-diffusers#performance-benchmarks)와 커뮤니티에서 제공하는 일부 [추가 측정](https://github.com/huggingface/swift-coreml-diffusers/issues/31)을 참조하십시오.
|
| 46 |
+
|
| 47 |
+
- 지원되는 추론 프레임워크
|
| 48 |
+
* `packages`는 Python 추론에 적합합니다. 네이티브 앱에 통합하기 전에 변환된 Core ML 모델을 테스트하거나, Core ML 성능을 알고 싶지만 네이티브 앱을 지원할 필요는 없는 경우에 사용할 수 있습니다. 예를 들어, 웹 UI가 있는 애플리케이션은 Python Core ML 백엔드를 완벽하게 사용할 수 있습니다.
|
| 49 |
+
* Swift 코��에는 `컴파일된` 모델이 필요합니다. Hub의 `컴파일된` 모델은 iOS 및 iPadOS 기기와의 호환성을 위해 큰 UNet 모델 가중치를 여러 파일로 분할합니다. 이는 [`--chunk-unet` 변환 옵션](https://github.com/apple/ml-stable-diffusion#-converting-models-to-core-ml)에 해당합니다. 네이티브 앱을 지원하려면 `컴파일된` 변형을 선택해야 합니다.
|
| 50 |
+
|
| 51 |
+
공식 Core ML Stable Diffusion [모델](https://huggingface.co/apple/coreml-stable-diffusion-v1-4/tree/main)에는 이러한 변형이 포함되어 있지만 커뮤니티 버전은 다를 수 있습니다:
|
| 52 |
+
|
| 53 |
+
```
|
| 54 |
+
coreml-stable-diffusion-v1-4
|
| 55 |
+
├── README.md
|
| 56 |
+
├── original
|
| 57 |
+
│ ├── compiled
|
| 58 |
+
│ └── packages
|
| 59 |
+
└── split_einsum
|
| 60 |
+
├── compiled
|
| 61 |
+
└── packages
|
| 62 |
+
```
|
| 63 |
+
|
| 64 |
+
아래와 같이 필요한 변형을 다운로드하여 사용할 수 있습니다.
|
| 65 |
+
|
| 66 |
+
## Python에서 Core ML 추론
|
| 67 |
+
|
| 68 |
+
Python에서 Core ML 추론을 실행하려면 다음 라이브러리를 설치하세요:
|
| 69 |
+
|
| 70 |
+
```bash
|
| 71 |
+
pip install huggingface_hub
|
| 72 |
+
pip install git+https://github.com/apple/ml-stable-diffusion
|
| 73 |
+
```
|
| 74 |
+
|
| 75 |
+
### 모델 체크포인트 다운로드하기
|
| 76 |
+
|
| 77 |
+
`컴파일된` 버전은 Swift와만 호환되므로 Python에서 추론을 실행하려면 `packages` 폴더에 저장된 버전 중 하나를 사용하세요. `원본` 또는 `split_einsum` 어텐션 중 어느 것을 사용할지 선택할 수 있습니다.
|
| 78 |
+
|
| 79 |
+
다음은 Hub에서 'models'라는 디렉토리로 'original' 어텐션 변형을 다운로드하는 방법입니다:
|
| 80 |
+
|
| 81 |
+
```Python
|
| 82 |
+
from huggingface_hub import snapshot_download
|
| 83 |
+
from pathlib import Path
|
| 84 |
+
|
| 85 |
+
repo_id = "apple/coreml-stable-diffusion-v1-4"
|
| 86 |
+
variant = "original/packages"
|
| 87 |
+
|
| 88 |
+
model_path = Path("./models") / (repo_id.split("/")[-1] + "_" + variant.replace("/", "_"))
|
| 89 |
+
snapshot_download(repo_id, allow_patterns=f"{variant}/*", local_dir=model_path, local_dir_use_symlinks=False)
|
| 90 |
+
print(f"Model downloaded at {model_path}")
|
| 91 |
+
```
|
| 92 |
+
|
| 93 |
+
|
| 94 |
+
### 추론[[python-inference]]
|
| 95 |
+
|
| 96 |
+
모델의 snapshot을 다운로드한 후에는 Apple의 Python 스크립트를 사용하여 테스트할 수 있습니다.
|
| 97 |
+
|
| 98 |
+
```shell
|
| 99 |
+
python -m python_coreml_stable_diffusion.pipeline --prompt "a photo of an astronaut riding a horse on mars" -i models/coreml-stable-diffusion-v1-4_original_packages -o </path/to/output/image> --compute-unit CPU_AND_GPU --seed 93
|
| 100 |
+
```
|
| 101 |
+
|
| 102 |
+
`<output-mlpackages-directory>`는 위 단계에서 다운로드한 체크포인트를 가리켜야 하며, `--compute-unit`은 추론을 허용할 하드웨어를 나타냅니다. 이는 다음 옵션 중 하나이어야 합니다: `ALL`, `CPU_AND_GPU`, `CPU_ONLY`, `CPU_AND_NE`. 선택적 출력 경로와 재현성을 위한 시드를 제공할 수도 있습니다.
|
| 103 |
+
|
| 104 |
+
추론 스크립트에서는 Stable Diffusion 모델의 원래 버전인 `CompVis/stable-diffusion-v1-4`를 사용한다고 가정합니다. 다른 모델을 사용하는 경우 추론 명령줄에서 `--model-version` 옵션을 사용하여 해당 허브 ID를 *지정*해야 합니다. 이는 이미 지원되는 모델과 사용자가 직접 학습하거나 파인튜닝한 사용자 지정 모델에 적용됩니다.
|
| 105 |
+
|
| 106 |
+
예를 들어, [`stable-diffusion-v1-5/stable-diffusion-v1-5`](https://huggingface.co/stable-diffusion-v1-5/stable-diffusion-v1-5)를 사용하려는 경우입니다:
|
| 107 |
+
|
| 108 |
+
```shell
|
| 109 |
+
python -m python_coreml_stable_diffusion.pipeline --prompt "a photo of an astronaut riding a horse on mars" --compute-unit ALL -o output --seed 93 -i models/coreml-stable-diffusion-v1-5_original_packages --model-version stable-diffusion-v1-5/stable-diffusion-v1-5
|
| 110 |
+
```
|
| 111 |
+
|
| 112 |
+
|
| 113 |
+
## Swift에서 Core ML 추론하기
|
| 114 |
+
|
| 115 |
+
Swift에서 추론을 실행하는 것은 모델이 이미 `mlmodelc` 형식으로 컴파일되어 있기 때문에 Python보다 약간 빠릅니다. 이는 앱이 시작될 때 모델이 불러와지는 것이 눈에 띄지만, 이후 여러 번 실행하면 눈에 띄지 않을 것입니다.
|
| 116 |
+
|
| 117 |
+
### 다운로드
|
| 118 |
+
|
| 119 |
+
Mac에서 Swift에서 추론을 실행하려면 `컴파일된` 체크포인트 버전 중 하나가 필요합니다. 이전 예제와 유사하지만 `컴파일된` 변형 중 하나를 사용하여 Python 코드를 로컬로 다운로드하는 것이 좋습니다:
|
| 120 |
+
|
| 121 |
+
```Python
|
| 122 |
+
from huggingface_hub import snapshot_download
|
| 123 |
+
from pathlib import Path
|
| 124 |
+
|
| 125 |
+
repo_id = "apple/coreml-stable-diffusion-v1-4"
|
| 126 |
+
variant = "original/compiled"
|
| 127 |
+
|
| 128 |
+
model_path = Path("./models") / (repo_id.split("/")[-1] + "_" + variant.replace("/", "_"))
|
| 129 |
+
snapshot_download(repo_id, allow_patterns=f"{variant}/*", local_dir=model_path, local_dir_use_symlinks=False)
|
| 130 |
+
print(f"Model downloaded at {model_path}")
|
| 131 |
+
```
|
| 132 |
+
|
| 133 |
+
### 추론[[swift-inference]]
|
| 134 |
+
|
| 135 |
+
추론을 실행하기 위해서, Apple의 리포지토리를 복제하세요:
|
| 136 |
+
|
| 137 |
+
```bash
|
| 138 |
+
git clone https://github.com/apple/ml-stable-diffusion
|
| 139 |
+
cd ml-stable-diffusion
|
| 140 |
+
```
|
| 141 |
+
|
| 142 |
+
그 다음 Apple의 명령어 도구인 [Swift 패키지 관리자](https://www.swift.org/package-manager/#)를 사용합니다:
|
| 143 |
+
|
| 144 |
+
```bash
|
| 145 |
+
swift run StableDiffusionSample --resource-path models/coreml-stable-diffusion-v1-4_original_compiled --compute-units all "a photo of an astronaut riding a horse on mars"
|
| 146 |
+
```
|
| 147 |
+
|
| 148 |
+
`--resource-path`에 이전 단계에서 다운로드한 체크포인트 중 하나를 지정해야 하므로 확장자가 `.mlmodelc`인 컴파일된 Core ML 번들이 포함되어 있는지 확인하시기 바랍니다. `--compute-units`는 다음 값 중 하나이어야 합니다: `all`, `cpuOnly`, `cpuAndGPU`, `cpuAndNeuralEngine`.
|
| 149 |
+
|
| 150 |
+
자세한 내용은 [Apple의 리포지토리 안의 지침](https://github.com/apple/ml-stable-diffusion)을 참고하시기 바랍니다.
|
| 151 |
+
|
| 152 |
+
|
| 153 |
+
## 지원되는 Diffusers 기능
|
| 154 |
+
|
| 155 |
+
Core ML 모델과 추론 코드는 🧨 Diffusers의 많은 기능, 옵션 및 유연성을 지원하지 않습니다. 다음은 유의해야 할 몇 가지 제한 사항입니다:
|
| 156 |
+
|
| 157 |
+
- Core ML 모델은 추론에만 적합합니다. 학습이나 파인튜닝에는 사용할 수 없습니다.
|
| 158 |
+
- Swift에 포팅된 스케줄러는 Stable Diffusion에서 사용하는 기본 스케줄러와 `diffusers` 구현에서 Swift로 포팅한 `DPMSolverMultistepScheduler` 두 개뿐입니다. 이들 중 약 절반의 스텝으로 동일한 품질을 생성하는 `DPMSolverMultistepScheduler`를 사용하는 것이 좋습니다.
|
| 159 |
+
- 추론 코드에서 네거티브 프롬프트, classifier-free guidance scale 및 image-to-image 작업을 사용할 수 있습니다. depth guidance, ControlNet, latent upscalers와 같은 고급 기능은 아직 사용할 수 없습니다.
|
| 160 |
+
|
| 161 |
+
Apple의 [변환 및 추론 리포지토리](https://github.com/apple/ml-stable-diffusion)와 자체 [swift-coreml-diffusers](https://github.com/huggingface/swift-coreml-diffusers) 리포지토리는 다른 개발자들이 구축할 수 있는 기술적인 데모입니다.
|
| 162 |
+
|
| 163 |
+
누락된 기능이 있다고 생각되면 언제든지 기능을 요청하거나, 더 좋은 방법은 기여 PR을 열어주세요. :)
|
| 164 |
+
|
| 165 |
+
|
| 166 |
+
## 네이티브 Diffusers Swift 앱
|
| 167 |
+
|
| 168 |
+
자체 Apple 하드웨어에서 Stable Diffusion을 실행하는 쉬운 방법 중 하나는 `diffusers`와 Apple의 변환 및 추론 리포지토리를 기반으로 하는 [자체 오픈 소스 Swift 리포지토리](https://github.com/huggingface/swift-coreml-diffusers)를 사용하는 것입니다. 코드를 공부하고 [Xcode](https://developer.apple.com/xcode/)로 컴파일하여 필요에 맞게 조정할 수 있습니다. 편의를 위해 앱스토어에 [독립형 Mac 앱](https://apps.apple.com/app/diffusers/id1666309574)도 있으므로 코드나 IDE를 다루지 않고도 사용할 수 있습니다. 개발자로서 Core ML이 Stable Diffusion 앱을 구축하는 데 가장 적합한 솔루션이라고 판단했다면, 이 가이드의 나머지 부분을 사용하여 프로젝트를 시작할 수 있습니다. 여러분이 무엇을 빌드할지 기대됩니다. :)
|
tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/optimization/fp16.md
ADDED
|
@@ -0,0 +1,410 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2024 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# 메모리와 속도
|
| 14 |
+
|
| 15 |
+
메모리 또는 속도에 대해 🤗 Diffusers *추론*을 최적화하기 위한 몇 가지 기술과 아이디어를 제시합니다.
|
| 16 |
+
일반적으로, memory-efficient attention을 위해 [xFormers](https://github.com/facebookresearch/xformers) 사용을 추천하기 때문에, 추천하는 [설치 방법](xformers)을 보고 설치해 보세요.
|
| 17 |
+
|
| 18 |
+
다음 설정이 성능과 메모리에 미치는 영향에 대해 설명합니다.
|
| 19 |
+
|
| 20 |
+
| | 지연시간 | 속도 향상 |
|
| 21 |
+
| ---------------- | ------- | ------- |
|
| 22 |
+
| 별도 설정 없음 | 9.50s | x1 |
|
| 23 |
+
| cuDNN auto-tuner | 9.37s | x1.01 |
|
| 24 |
+
| fp16 | 3.61s | x2.63 |
|
| 25 |
+
| Channels Last 메모리 형식 | 3.30s | x2.88 |
|
| 26 |
+
| traced UNet | 3.21s | x2.96 |
|
| 27 |
+
| memory-efficient attention | 2.63s | x3.61 |
|
| 28 |
+
|
| 29 |
+
<em>
|
| 30 |
+
NVIDIA TITAN RTX에서 50 DDIM 스텝의 "a photo of an astronaut riding a horse on mars" 프롬프트로 512x512 크기의 단일 이미지를 생성하였습니다.
|
| 31 |
+
</em>
|
| 32 |
+
|
| 33 |
+
## cuDNN auto-tuner 활성화하기
|
| 34 |
+
|
| 35 |
+
[NVIDIA cuDNN](https://developer.nvidia.com/cudnn)은 컨볼루션을 계산하는 많은 알고리즘을 지원합니다. Autotuner는 짧은 벤치마크를 실행하고 주어진 입력 크기에 대해 주어진 하드웨어에서 최고의 성능을 가진 커널을 선택합니다.
|
| 36 |
+
|
| 37 |
+
**컨볼루션 네트워크**를 활용하고 있기 때문에 (다른 유형들은 현재 지원되지 않음), 다음 설정을 통해 추론 전에 cuDNN autotuner를 활성화할 수 있습니다:
|
| 38 |
+
|
| 39 |
+
```python
|
| 40 |
+
import torch
|
| 41 |
+
|
| 42 |
+
torch.backends.cudnn.benchmark = True
|
| 43 |
+
```
|
| 44 |
+
|
| 45 |
+
### fp32 대신 tf32 사용하기 (Ampere 및 이후 CUDA 장치들에서)
|
| 46 |
+
|
| 47 |
+
Ampere 및 이후 CUDA 장치에서 행렬곱 및 컨볼루션은 TensorFloat32(TF32) 모드를 사용하여 더 빠르지만 약간 덜 정확할 수 있습니다.
|
| 48 |
+
기본적으로 PyTorch는 컨볼루션에 대해 TF32 모드를 활성화하지만 행렬 곱셈은 활성화하지 않습니다.
|
| 49 |
+
네트워크에 완전한 float32 정밀도가 필요한 경우가 아니면 행렬 곱셈에 대해서도 이 설정을 활성화하는 것이 좋습니다.
|
| 50 |
+
이는 일반적으로 무시할 수 있는 수치의 정확도 손실이 있지만, 계산 속도를 크게 높일 수 있습니다.
|
| 51 |
+
그것에 대해 [여기](https://huggingface.co/docs/transformers/v4.18.0/en/performance#tf32)서 더 읽을 수 있습니다.
|
| 52 |
+
추론하기 전에 다음을 추가하기만 하면 됩니다:
|
| 53 |
+
|
| 54 |
+
```python
|
| 55 |
+
import torch
|
| 56 |
+
|
| 57 |
+
torch.backends.cuda.matmul.allow_tf32 = True
|
| 58 |
+
```
|
| 59 |
+
|
| 60 |
+
## 반정밀도 가중치
|
| 61 |
+
|
| 62 |
+
더 많은 GPU 메모리를 절약하고 더 빠른 속도를 얻기 위해 모델 가중치를 반정밀도(half precision)로 직접 불러오고 실행할 수 있습니다.
|
| 63 |
+
여기에는 `fp16`이라는 브랜치에 저장된 float16 버전의 가중치를 불러오고, 그 때 `float16` 유형을 사용하도록 PyTorch에 지시하는 작업이 포함됩니다.
|
| 64 |
+
|
| 65 |
+
```Python
|
| 66 |
+
pipe = StableDiffusionPipeline.from_pretrained(
|
| 67 |
+
"stable-diffusion-v1-5/stable-diffusion-v1-5",
|
| 68 |
+
|
| 69 |
+
torch_dtype=torch.float16,
|
| 70 |
+
)
|
| 71 |
+
pipe = pipe.to("cuda")
|
| 72 |
+
|
| 73 |
+
prompt = "a photo of an astronaut riding a horse on mars"
|
| 74 |
+
image = pipe(prompt).images[0]
|
| 75 |
+
```
|
| 76 |
+
|
| 77 |
+
<Tip warning={true}>
|
| 78 |
+
어떤 파이프라인에서도 [`torch.autocast`](https://pytorch.org/docs/stable/amp.html#torch.autocast) 를 사용하는 것은 검은색 이미지를 생성할 수 있고, 순수한 float16 정밀도를 사용하는 것보다 항상 느리기 때문에 사용하지 않는 것이 좋습니다.
|
| 79 |
+
</Tip>
|
| 80 |
+
|
| 81 |
+
## 추가 메모리 절약을 위한 슬라이스 어텐션
|
| 82 |
+
|
| 83 |
+
추가 메모리 절약을 위해, 한 번에 모두 계산하는 대신 단계적으로 계산을 수행하는 슬라이스 버전의 어텐션(attention)을 사용할 수 있습니다.
|
| 84 |
+
|
| 85 |
+
<Tip>
|
| 86 |
+
Attention slicing은 모델이 하나 이상의 어텐션 헤드를 사용하는 한, 배치 크기가 1인 경우에도 유용합니다.
|
| 87 |
+
하나 이상의 어텐션 헤드가 있는 경우 *QK^T* 어텐션 매트릭스는 상당한 양의 메모리를 절약할 수 있는 각 헤드에 대해 순차적으로 계산될 수 있습니다.
|
| 88 |
+
</Tip>
|
| 89 |
+
|
| 90 |
+
각 헤드에 대해 순차적으로 어텐션 계산을 수행하려면, 다음과 같이 추론 전에 파이프라인에서 [`~StableDiffusionPipeline.enable_attention_slicing`]를 호출하면 됩니다:
|
| 91 |
+
|
| 92 |
+
```Python
|
| 93 |
+
import torch
|
| 94 |
+
from diffusers import StableDiffusionPipeline
|
| 95 |
+
|
| 96 |
+
pipe = StableDiffusionPipeline.from_pretrained(
|
| 97 |
+
"stable-diffusion-v1-5/stable-diffusion-v1-5",
|
| 98 |
+
|
| 99 |
+
torch_dtype=torch.float16,
|
| 100 |
+
)
|
| 101 |
+
pipe = pipe.to("cuda")
|
| 102 |
+
|
| 103 |
+
prompt = "a photo of an astronaut riding a horse on mars"
|
| 104 |
+
pipe.enable_attention_slicing()
|
| 105 |
+
image = pipe(prompt).images[0]
|
| 106 |
+
```
|
| 107 |
+
|
| 108 |
+
추론 시간이 약 10% 느려지는 약간의 성능 저하가 있지만 이 방법을 사용하면 3.2GB 정도의 작은 VRAM으로도 Stable Diffusion을 사용할 수 있습니다!
|
| 109 |
+
|
| 110 |
+
|
| 111 |
+
## 더 큰 배치를 위한 sliced VAE 디코드
|
| 112 |
+
|
| 113 |
+
제한된 VRAM에서 대규모 이미지 배치를 디코딩하거나 32개 이상의 이미지가 포함된 배치를 활성화하기 위해, 배치의 latent 이미지를 한 번에 하나씩 디코딩하는 슬라이스 VAE 디코드를 사용할 수 있습니다.
|
| 114 |
+
|
| 115 |
+
이를 [`~StableDiffusionPipeline.enable_attention_slicing`] 또는 [`~StableDiffusionPipeline.enable_xformers_memory_efficient_attention`]과 결합하여 메모리 사용을 추가로 최소화할 수 있습니다.
|
| 116 |
+
|
| 117 |
+
VAE 디코드를 한 번에 하나씩 수행하려면 추론 전에 파이프라인에서 [`~StableDiffusionPipeline.enable_vae_slicing`]을 호출합니다. 예를 들어:
|
| 118 |
+
|
| 119 |
+
```Python
|
| 120 |
+
import torch
|
| 121 |
+
from diffusers import StableDiffusionPipeline
|
| 122 |
+
|
| 123 |
+
pipe = StableDiffusionPipeline.from_pretrained(
|
| 124 |
+
"stable-diffusion-v1-5/stable-diffusion-v1-5",
|
| 125 |
+
|
| 126 |
+
torch_dtype=torch.float16,
|
| 127 |
+
)
|
| 128 |
+
pipe = pipe.to("cuda")
|
| 129 |
+
|
| 130 |
+
prompt = "a photo of an astronaut riding a horse on mars"
|
| 131 |
+
pipe.enable_vae_slicing()
|
| 132 |
+
images = pipe([prompt] * 32).images
|
| 133 |
+
```
|
| 134 |
+
|
| 135 |
+
다중 이미지 배치에서 VAE 디코드가 약간의 성능 향상이 이루어집니다. 단일 이미지 배치에서는 성능 영향은 없습니다.
|
| 136 |
+
|
| 137 |
+
|
| 138 |
+
<a name="sequential_offloading"></a>
|
| 139 |
+
## 메모리 절약을 위해 가속 기능을 사용하여 CPU로 오프로딩
|
| 140 |
+
|
| 141 |
+
추가 메모리 절약을 위해 가중치를 CPU로 오프로드하고 순방향 전달을 수행할 때만 GPU로 로드할 수 있습니다.
|
| 142 |
+
|
| 143 |
+
CPU 오프로딩을 수행하려면 [`~StableDiffusionPipeline.enable_sequential_cpu_offload`]를 호출하기만 하면 됩니다:
|
| 144 |
+
|
| 145 |
+
```Python
|
| 146 |
+
import torch
|
| 147 |
+
from diffusers import StableDiffusionPipeline
|
| 148 |
+
|
| 149 |
+
pipe = StableDiffusionPipeline.from_pretrained(
|
| 150 |
+
"stable-diffusion-v1-5/stable-diffusion-v1-5",
|
| 151 |
+
|
| 152 |
+
torch_dtype=torch.float16,
|
| 153 |
+
)
|
| 154 |
+
|
| 155 |
+
prompt = "a photo of an astronaut riding a horse on mars"
|
| 156 |
+
pipe.enable_sequential_cpu_offload()
|
| 157 |
+
image = pipe(prompt).images[0]
|
| 158 |
+
```
|
| 159 |
+
|
| 160 |
+
그러면 메모리 소비를 3GB 미만으로 줄일 수 있습니다.
|
| 161 |
+
|
| 162 |
+
참고로 이 방법은 전체 모델이 아닌 서브모듈 수준에서 작동합니다. 이는 메모리 소비를 최소화하는 가장 좋은 방법이지만 프로세스의 반복적 특성으로 인해 추론 속도가 훨씬 느립니다. 파이프라인의 UNet 구성 요소는 여러 번 실행됩니다('num_inference_steps' 만큼). 매번 UNet의 서로 다른 서브모듈이 순차적으로 온로드된 다음 필요에 따라 오프로드되므로 메모리 이동 횟수가 많습니다.
|
| 163 |
+
|
| 164 |
+
<Tip>
|
| 165 |
+
또 다른 최적화 방법인 <a href="#model_offloading">모델 오프로딩</a>을 사용하는 것을 고려하십시오. 이는 훨씬 빠르지만 메모리 절약이 크지는 않습니다.
|
| 166 |
+
</Tip>
|
| 167 |
+
|
| 168 |
+
또한 ttention slicing과 연결해서 최소 메모리(< 2GB)로도 동작할 수 있습니다.
|
| 169 |
+
|
| 170 |
+
|
| 171 |
+
```Python
|
| 172 |
+
import torch
|
| 173 |
+
from diffusers import StableDiffusionPipeline
|
| 174 |
+
|
| 175 |
+
pipe = StableDiffusionPipeline.from_pretrained(
|
| 176 |
+
"stable-diffusion-v1-5/stable-diffusion-v1-5",
|
| 177 |
+
|
| 178 |
+
torch_dtype=torch.float16,
|
| 179 |
+
)
|
| 180 |
+
|
| 181 |
+
prompt = "a photo of an astronaut riding a horse on mars"
|
| 182 |
+
pipe.enable_sequential_cpu_offload()
|
| 183 |
+
pipe.enable_attention_slicing(1)
|
| 184 |
+
|
| 185 |
+
image = pipe(prompt).images[0]
|
| 186 |
+
```
|
| 187 |
+
|
| 188 |
+
**참고**: 'enable_sequential_cpu_offload()'를 사용할 때, 미리 파이프라인을 CUDA로 이동하지 **않는** 것이 중요합니다.그렇지 않으면 메모리 소비의 이득이 최소화됩니다. 더 많은 정보를 위해 [이 이슈](https://github.com/huggingface/diffusers/issues/1934)를 보세요.
|
| 189 |
+
|
| 190 |
+
<a name="model_offloading"></a>
|
| 191 |
+
## 빠른 추론과 메모리 메모리 절약을 위한 모델 오프로딩
|
| 192 |
+
|
| 193 |
+
[순차적 CPU 오프로딩](#sequential_offloading)은 이전 섹션에서 설명한 것처럼 많은 메모리를 보존하지만 필요에 따라 서브모듈을 GPU로 이동하고 새 모듈이 실행될 때 즉시 CPU로 반환되기 때문에 추론 속도가 느려집니다.
|
| 194 |
+
|
| 195 |
+
전체 모델 오프로딩은 각 모델의 구성 요소인 _modules_을 처리하는 대신, 전체 모델을 GPU로 이동하는 대안입니다. 이로 인해 추론 시간에 미치는 영향은 미미하지만(파이프라인을 'cuda'로 이동하는 것과 비교하여) 여전히 약간의 메모리를 절약할 수 있습니다.
|
| 196 |
+
|
| 197 |
+
이 시나리오에서는 파이프라인의 주요 구성 요소 중 하나만(일반적으로 텍스트 인코더, unet 및 vae) GPU에 있고, 나머지는 CPU에서 대기할 것입니다.
|
| 198 |
+
여러 반복을 위해 실행되는 UNet과 같은 구성 요소는 더 이상 필요하지 않을 때까지 GPU에 남아 있습니다.
|
| 199 |
+
|
| 200 |
+
이 기능은 아래와 같이 파이프라인에서 `enable_model_cpu_offload()`를 호출하여 활성화할 수 있습니다.
|
| 201 |
+
|
| 202 |
+
```Python
|
| 203 |
+
import torch
|
| 204 |
+
from diffusers import StableDiffusionPipeline
|
| 205 |
+
|
| 206 |
+
pipe = StableDiffusionPipeline.from_pretrained(
|
| 207 |
+
"stable-diffusion-v1-5/stable-diffusion-v1-5",
|
| 208 |
+
torch_dtype=torch.float16,
|
| 209 |
+
)
|
| 210 |
+
|
| 211 |
+
prompt = "a photo of an astronaut riding a horse on mars"
|
| 212 |
+
pipe.enable_model_cpu_offload()
|
| 213 |
+
image = pipe(prompt).images[0]
|
| 214 |
+
```
|
| 215 |
+
|
| 216 |
+
이는 추가적인 메모리 절약을 위한 attention slicing과도 호환됩니다.
|
| 217 |
+
|
| 218 |
+
```Python
|
| 219 |
+
import torch
|
| 220 |
+
from diffusers import StableDiffusionPipeline
|
| 221 |
+
|
| 222 |
+
pipe = StableDiffusionPipeline.from_pretrained(
|
| 223 |
+
"stable-diffusion-v1-5/stable-diffusion-v1-5",
|
| 224 |
+
torch_dtype=torch.float16,
|
| 225 |
+
)
|
| 226 |
+
|
| 227 |
+
prompt = "a photo of an astronaut riding a horse on mars"
|
| 228 |
+
pipe.enable_model_cpu_offload()
|
| 229 |
+
pipe.enable_attention_slicing(1)
|
| 230 |
+
|
| 231 |
+
image = pipe(prompt).images[0]
|
| 232 |
+
```
|
| 233 |
+
|
| 234 |
+
<Tip>
|
| 235 |
+
이 기능을 사용하려면 'accelerate' 버전 0.17.0 이상이 필요합니다.
|
| 236 |
+
</Tip>
|
| 237 |
+
|
| 238 |
+
## Channels Last 메모리 형식 사용하기
|
| 239 |
+
|
| 240 |
+
Channels Last 메모리 형식은 차원 순서를 보존하는 메모리에서 NCHW 텐서 배열을 대체하는 방법입니다.
|
| 241 |
+
Channels Last 텐서는 채널이 가장 조밀한 차원이 되는 방식으로 정렬됩니다(일명 픽셀당 이미지를 저장).
|
| 242 |
+
현재 모든 연산자 Channels Last 형식을 지원하는 것은 아니라 성능이 저하될 수 있으므로, 사용해보고 모델에 잘 작동하는지 확인하는 것이 좋습니다.
|
| 243 |
+
|
| 244 |
+
|
| 245 |
+
예를 들어 파이프라인의 UNet 모델이 channels Last 형식을 사용하도록 설정하려면 다음을 사용할 수 있습니다:
|
| 246 |
+
|
| 247 |
+
```python
|
| 248 |
+
print(pipe.unet.conv_out.state_dict()["weight"].stride()) # (2880, 9, 3, 1)
|
| 249 |
+
pipe.unet.to(memory_format=torch.channels_last) # in-place 연산
|
| 250 |
+
# 2번째 차원에서 스트라이드 1을 가지는 (2880, 1, 960, 320)로, 연산이 작동함을 증명합니다.
|
| 251 |
+
print(pipe.unet.conv_out.state_dict()["weight"].stride())
|
| 252 |
+
```
|
| 253 |
+
|
| 254 |
+
## 추적(tracing)
|
| 255 |
+
|
| 256 |
+
추적은 모델을 통해 예제 입력 텐서를 통해 실행되는데, 해당 입력이 모델의 레이어를 통과할 때 호출되는 작업을 캡처하여 실행 파일 또는 'ScriptFunction'이 반환되도록 하고, 이는 just-in-time 컴파일로 최적화됩니다.
|
| 257 |
+
|
| 258 |
+
UNet 모델을 추적하기 위해 다음을 사용할 수 있습니다:
|
| 259 |
+
|
| 260 |
+
```python
|
| 261 |
+
import time
|
| 262 |
+
import torch
|
| 263 |
+
from diffusers import StableDiffusionPipeline
|
| 264 |
+
import functools
|
| 265 |
+
|
| 266 |
+
# torch 기울기 비활성화
|
| 267 |
+
torch.set_grad_enabled(False)
|
| 268 |
+
|
| 269 |
+
# 변수 설정
|
| 270 |
+
n_experiments = 2
|
| 271 |
+
unet_runs_per_experiment = 50
|
| 272 |
+
|
| 273 |
+
|
| 274 |
+
# 입력 불러오기
|
| 275 |
+
def generate_inputs():
|
| 276 |
+
sample = torch.randn((2, 4, 64, 64), device="cuda", dtype=torch.float16)
|
| 277 |
+
timestep = torch.rand(1, device="cuda", dtype=torch.float16) * 999
|
| 278 |
+
encoder_hidden_states = torch.randn((2, 77, 768), device="cuda", dtype=torch.float16)
|
| 279 |
+
return sample, timestep, encoder_hidden_states
|
| 280 |
+
|
| 281 |
+
|
| 282 |
+
pipe = StableDiffusionPipeline.from_pretrained(
|
| 283 |
+
"stable-diffusion-v1-5/stable-diffusion-v1-5",
|
| 284 |
+
torch_dtype=torch.float16,
|
| 285 |
+
).to("cuda")
|
| 286 |
+
unet = pipe.unet
|
| 287 |
+
unet.eval()
|
| 288 |
+
unet.to(memory_format=torch.channels_last) # Channels Last 메모리 형식 사용
|
| 289 |
+
unet.forward = functools.partial(unet.forward, return_dict=False) # return_dict=False을 기본값으로 설정
|
| 290 |
+
|
| 291 |
+
# 워밍업
|
| 292 |
+
for _ in range(3):
|
| 293 |
+
with torch.inference_mode():
|
| 294 |
+
inputs = generate_inputs()
|
| 295 |
+
orig_output = unet(*inputs)
|
| 296 |
+
|
| 297 |
+
# 추적
|
| 298 |
+
print("tracing..")
|
| 299 |
+
unet_traced = torch.jit.trace(unet, inputs)
|
| 300 |
+
unet_traced.eval()
|
| 301 |
+
print("done tracing")
|
| 302 |
+
|
| 303 |
+
|
| 304 |
+
# 워밍업 및 그래프 최적화
|
| 305 |
+
for _ in range(5):
|
| 306 |
+
with torch.inference_mode():
|
| 307 |
+
inputs = generate_inputs()
|
| 308 |
+
orig_output = unet_traced(*inputs)
|
| 309 |
+
|
| 310 |
+
|
| 311 |
+
# 벤치마킹
|
| 312 |
+
with torch.inference_mode():
|
| 313 |
+
for _ in range(n_experiments):
|
| 314 |
+
torch.cuda.synchronize()
|
| 315 |
+
start_time = time.time()
|
| 316 |
+
for _ in range(unet_runs_per_experiment):
|
| 317 |
+
orig_output = unet_traced(*inputs)
|
| 318 |
+
torch.cuda.synchronize()
|
| 319 |
+
print(f"unet traced inference took {time.time() - start_time:.2f} seconds")
|
| 320 |
+
for _ in range(n_experiments):
|
| 321 |
+
torch.cuda.synchronize()
|
| 322 |
+
start_time = time.time()
|
| 323 |
+
for _ in range(unet_runs_per_experiment):
|
| 324 |
+
orig_output = unet(*inputs)
|
| 325 |
+
torch.cuda.synchronize()
|
| 326 |
+
print(f"unet inference took {time.time() - start_time:.2f} seconds")
|
| 327 |
+
|
| 328 |
+
# 모델 저장
|
| 329 |
+
unet_traced.save("unet_traced.pt")
|
| 330 |
+
```
|
| 331 |
+
|
| 332 |
+
그 다음, 파이프라인의 `unet` 특성을 다음과 같이 추적된 모델로 바꿀 수 있습니다.
|
| 333 |
+
|
| 334 |
+
```python
|
| 335 |
+
from diffusers import StableDiffusionPipeline
|
| 336 |
+
import torch
|
| 337 |
+
from dataclasses import dataclass
|
| 338 |
+
|
| 339 |
+
|
| 340 |
+
@dataclass
|
| 341 |
+
class UNet2DConditionOutput:
|
| 342 |
+
sample: torch.Tensor
|
| 343 |
+
|
| 344 |
+
|
| 345 |
+
pipe = StableDiffusionPipeline.from_pretrained(
|
| 346 |
+
"stable-diffusion-v1-5/stable-diffusion-v1-5",
|
| 347 |
+
torch_dtype=torch.float16,
|
| 348 |
+
).to("cuda")
|
| 349 |
+
|
| 350 |
+
# jitted unet 사용
|
| 351 |
+
unet_traced = torch.jit.load("unet_traced.pt")
|
| 352 |
+
|
| 353 |
+
|
| 354 |
+
# pipe.unet 삭제
|
| 355 |
+
class TracedUNet(torch.nn.Module):
|
| 356 |
+
def __init__(self):
|
| 357 |
+
super().__init__()
|
| 358 |
+
self.in_channels = pipe.unet.config.in_channels
|
| 359 |
+
self.device = pipe.unet.device
|
| 360 |
+
|
| 361 |
+
def forward(self, latent_model_input, t, encoder_hidden_states):
|
| 362 |
+
sample = unet_traced(latent_model_input, t, encoder_hidden_states)[0]
|
| 363 |
+
return UNet2DConditionOutput(sample=sample)
|
| 364 |
+
|
| 365 |
+
|
| 366 |
+
pipe.unet = TracedUNet()
|
| 367 |
+
|
| 368 |
+
with torch.inference_mode():
|
| 369 |
+
image = pipe([prompt] * 1, num_inference_steps=50).images[0]
|
| 370 |
+
```
|
| 371 |
+
|
| 372 |
+
|
| 373 |
+
## Memory-efficient attention
|
| 374 |
+
|
| 375 |
+
어텐션 블록의 대역폭을 최적화하는 최근 작업으로 GPU 메모리 사용량이 크게 향상되고 향상되었습니다.
|
| 376 |
+
@tridao의 가장 최근의 플래시 어텐션: [code](https://github.com/HazyResearch/flash-attention), [paper](https://huggingface.co/papers/2205.14135).
|
| 377 |
+
|
| 378 |
+
배치 크기 1(프롬프트 1개)의 512x512 크기로 추론을 실행할 때 몇 가지 Nvidia GPU에서 얻은 속도 향상은 다음과 같습니다:
|
| 379 |
+
|
| 380 |
+
| GPU | 기준 어텐션 FP16 | 메모리 효율적인 어텐션 FP16 |
|
| 381 |
+
|------------------ |--------------------- |--------------------------------- |
|
| 382 |
+
| NVIDIA Tesla T4 | 3.5it/s | 5.5it/s |
|
| 383 |
+
| NVIDIA 3060 RTX | 4.6it/s | 7.8it/s |
|
| 384 |
+
| NVIDIA A10G | 8.88it/s | 15.6it/s |
|
| 385 |
+
| NVIDIA RTX A6000 | 11.7it/s | 21.09it/s |
|
| 386 |
+
| NVIDIA TITAN RTX | 12.51it/s | 18.22it/s |
|
| 387 |
+
| A100-SXM4-40GB | 18.6it/s | 29.it/s |
|
| 388 |
+
| A100-SXM-80GB | 18.7it/s | 29.5it/s |
|
| 389 |
+
|
| 390 |
+
이를 활용하려면 다음을 만족해야 합니다:
|
| 391 |
+
- PyTorch > 1.12
|
| 392 |
+
- Cuda 사용 가능
|
| 393 |
+
- [xformers 라이브러리를 설치함](xformers)
|
| 394 |
+
```python
|
| 395 |
+
from diffusers import StableDiffusionPipeline
|
| 396 |
+
import torch
|
| 397 |
+
|
| 398 |
+
pipe = StableDiffusionPipeline.from_pretrained(
|
| 399 |
+
"stable-diffusion-v1-5/stable-diffusion-v1-5",
|
| 400 |
+
torch_dtype=torch.float16,
|
| 401 |
+
).to("cuda")
|
| 402 |
+
|
| 403 |
+
pipe.enable_xformers_memory_efficient_attention()
|
| 404 |
+
|
| 405 |
+
with torch.inference_mode():
|
| 406 |
+
sample = pipe("a small cat")
|
| 407 |
+
|
| 408 |
+
# 선택: 이를 비활성화 하기 위해 다음을 사용할 수 있습니다.
|
| 409 |
+
# pipe.disable_xformers_memory_efficient_attention()
|
| 410 |
+
```
|
tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/optimization/habana.md
ADDED
|
@@ -0,0 +1,71 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2024 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Intel Gaudi에서 Stable Diffusion을 사용하는 방법
|
| 14 |
+
|
| 15 |
+
🤗 Diffusers는 🤗 [Optimum Habana](https://huggingface.co/docs/optimum/habana/usage_guides/stable_diffusion)를 통해서 Habana Gaudi와 호환됩니다.
|
| 16 |
+
|
| 17 |
+
## 요구 사항
|
| 18 |
+
|
| 19 |
+
- Optimum Habana 1.4 또는 이후, [여기](https://huggingface.co/docs/optimum/habana/installation)에 설치하는 방법이 있습니다.
|
| 20 |
+
- SynapseAI 1.8.
|
| 21 |
+
|
| 22 |
+
|
| 23 |
+
## 추론 파이프라인
|
| 24 |
+
|
| 25 |
+
Gaudi에서 Stable Diffusion 1 및 2로 이미지를 생성하려면 두 인스턴스를 인스턴스화해야 합니다:
|
| 26 |
+
- [`GaudiStableDiffusionPipeline`](https://huggingface.co/docs/optimum/habana/package_reference/stable_diffusion_pipeline)이 포함된 파이프라인. 이 파이프라인은 *텍스트-이미지 생성*을 지원합니다.
|
| 27 |
+
- [`GaudiDDIMScheduler`](https://huggingface.co/docs/optimum/habana/package_reference/stable_diffusion_pipeline#optimum.habana.diffusers.GaudiDDIMScheduler)이 포함된 스케줄러. 이 스케줄러는 Habana Gaudi에 최적화되어 있습니다.
|
| 28 |
+
|
| 29 |
+
파이프라인을 초기화할 때, HPU에 배포하기 위해 `use_habana=True`를 지정해야 합니다.
|
| 30 |
+
또한 가능한 가장 빠른 생성을 위해 `use_hpu_graphs=True`로 **HPU 그래프**를 활성화해야 합니다.
|
| 31 |
+
마지막으로, [Hugging Face Hub](https://huggingface.co/Habana)에서 다운로드할 수 있는 [Gaudi configuration](https://huggingface.co/docs/optimum/habana/package_reference/gaudi_config)을 지정해야 합니다.
|
| 32 |
+
|
| 33 |
+
```python
|
| 34 |
+
from optimum.habana import GaudiConfig
|
| 35 |
+
from optimum.habana.diffusers import GaudiDDIMScheduler, GaudiStableDiffusionPipeline
|
| 36 |
+
|
| 37 |
+
model_name = "stabilityai/stable-diffusion-2-base"
|
| 38 |
+
scheduler = GaudiDDIMScheduler.from_pretrained(model_name, subfolder="scheduler")
|
| 39 |
+
pipeline = GaudiStableDiffusionPipeline.from_pretrained(
|
| 40 |
+
model_name,
|
| 41 |
+
scheduler=scheduler,
|
| 42 |
+
use_habana=True,
|
| 43 |
+
use_hpu_graphs=True,
|
| 44 |
+
gaudi_config="Habana/stable-diffusion",
|
| 45 |
+
)
|
| 46 |
+
```
|
| 47 |
+
|
| 48 |
+
파이프라인을 호출하여 하나 이상의 프롬프트에서 배치별로 이미지를 생성할 수 있습니다.
|
| 49 |
+
|
| 50 |
+
```python
|
| 51 |
+
outputs = pipeline(
|
| 52 |
+
prompt=[
|
| 53 |
+
"High quality photo of an astronaut riding a horse in space",
|
| 54 |
+
"Face of a yellow cat, high resolution, sitting on a park bench",
|
| 55 |
+
],
|
| 56 |
+
num_images_per_prompt=10,
|
| 57 |
+
batch_size=4,
|
| 58 |
+
)
|
| 59 |
+
```
|
| 60 |
+
|
| 61 |
+
더 많은 정보를 얻기 위해, Optimum Habana의 [문서](https://huggingface.co/docs/optimum/habana/usage_guides/stable_diffusion)와 공식 GitHub 저장소에 제공된 [예시](https://github.com/huggingface/optimum-habana/tree/main/examples/stable-diffusion)를 확인하세요.
|
| 62 |
+
|
| 63 |
+
|
| 64 |
+
## 벤치마크
|
| 65 |
+
|
| 66 |
+
다음은 [Habana/stable-diffusion](https://huggingface.co/Habana/stable-diffusion) Gaudi 구성(혼합 정밀도 bf16/fp32)을 사용하는 Habana first-generation Gaudi 및 Gaudi2의 지연 시간입니다:
|
| 67 |
+
|
| 68 |
+
| | Latency (배치 크기 = 1) | Throughput (배치 크기 = 8) |
|
| 69 |
+
| ---------------------- |:------------------------:|:---------------------------:|
|
| 70 |
+
| first-generation Gaudi | 4.29s | 0.283 images/s |
|
| 71 |
+
| Gaudi2 | 1.54s | 0.904 images/s |
|
tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/optimization/mps.md
ADDED
|
@@ -0,0 +1,71 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2024 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Apple Silicon (M1/M2)에서 Stable Diffusion을 사용하는 방법
|
| 14 |
+
|
| 15 |
+
Diffusers는 Stable Diffusion 추론을 위해 PyTorch `mps`를 사용해 Apple 실리콘과 호환됩니다. 다음은 Stable Diffusion이 있는 M1 또는 M2 컴퓨터를 사용하기 위해 따라야 하는 단계입니다.
|
| 16 |
+
|
| 17 |
+
## 요구 사항
|
| 18 |
+
|
| 19 |
+
- Apple silicon (M1/M2) 하드웨어의 Mac 컴퓨터.
|
| 20 |
+
- macOS 12.6 또는 이후 (13.0 또는 이후 추천).
|
| 21 |
+
- Python arm64 버전
|
| 22 |
+
- PyTorch 2.0(추천) 또는 1.13(`mps`를 지원하는 최소 버전). Yhttps://pytorch.org/get-started/locally/의 지침에 따라 `pip` 또는 `conda`로 설치할 수 있습니다.
|
| 23 |
+
|
| 24 |
+
|
| 25 |
+
## 추론 파이프라인
|
| 26 |
+
|
| 27 |
+
아래 코도는 익숙한 `to()` 인터페이스를 사용하여 `mps` 백엔드로 Stable Diffusion 파이프라인을 M1 또는 M2 장치로 이동하는 방법을 보여줍니다.
|
| 28 |
+
|
| 29 |
+
|
| 30 |
+
<Tip warning={true}>
|
| 31 |
+
|
| 32 |
+
**PyTorch 1.13을 사용 중일 때 ** 추가 일회성 전달을 사용하여 파이프라인을 "프라이밍"하는 것을 추천합니다. 이것은 발견한 이상한 문제에 대한 임시 해결 방법입니다. 첫 번째 추론 전달은 후속 전달와 약간 다른 결과를 생성합니다. 이 전달은 한 번만 수행하면 되며 추론 단계를 한 번만 사용하고 결과를 폐기해도 됩니다.
|
| 33 |
+
|
| 34 |
+
</Tip>
|
| 35 |
+
|
| 36 |
+
이전 팁에서 설명한 것들을 포함한 여러 문제를 해결하므로 PyTorch 2 이상을 사용하는 것이 좋습니다.
|
| 37 |
+
|
| 38 |
+
|
| 39 |
+
```python
|
| 40 |
+
# `huggingface-cli login`에 로그인되어 있음을 확인
|
| 41 |
+
from diffusers import DiffusionPipeline
|
| 42 |
+
|
| 43 |
+
pipe = DiffusionPipeline.from_pretrained("stable-diffusion-v1-5/stable-diffusion-v1-5")
|
| 44 |
+
pipe = pipe.to("mps")
|
| 45 |
+
|
| 46 |
+
# 컴퓨터가 64GB 이하의 RAM 램일 때 추천
|
| 47 |
+
pipe.enable_attention_slicing()
|
| 48 |
+
|
| 49 |
+
prompt = "a photo of an astronaut riding a horse on mars"
|
| 50 |
+
|
| 51 |
+
# 처음 "워밍업" 전달 (위 설명을 보세요)
|
| 52 |
+
_ = pipe(prompt, num_inference_steps=1)
|
| 53 |
+
|
| 54 |
+
# 결과는 워밍업 전달 후의 CPU 장치의 결과와 일치합니다.
|
| 55 |
+
image = pipe(prompt).images[0]
|
| 56 |
+
```
|
| 57 |
+
|
| 58 |
+
## 성능 추천
|
| 59 |
+
|
| 60 |
+
M1/M2 성능은 메모리 압력에 매우 민감합니다. 시스템은 필요한 경우 자동으로 스왑되지만 스왑할 때 성능이 크게 저하됩니다.
|
| 61 |
+
|
| 62 |
+
|
| 63 |
+
특히 컴퓨터의 시스템 RAM이 64GB 미만이거나 512 × 512픽셀보다 큰 비표준 해상도에서 이미지를 생성하는 경우, 추론 중에 메모리 압력을 줄이고 스와핑을 방지하기 위해 *어텐션 슬라이싱*을 사용하는 것이 좋습니다. 어텐션 슬라이싱은 비용이 많이 드는 어텐션 작업을 한 번에 모두 수행하는 대신 여러 단계로 수행합니다. 일반적으로 범용 메모리가 없는 컴퓨터에서 ~20%의 성능 영향을 미치지만 64GB 이상이 아닌 경우 대부분의 Apple Silicon 컴퓨터에서 *더 나은 성능*이 관찰되었습니다.
|
| 64 |
+
|
| 65 |
+
```python
|
| 66 |
+
pipeline.enable_attention_slicing()
|
| 67 |
+
```
|
| 68 |
+
|
| 69 |
+
## Known Issues
|
| 70 |
+
|
| 71 |
+
- 여러 프롬프트를 배치로 생성하는 것은 [충돌이 발생하거나 안정적으로 작동하지 않습니다](https://github.com/huggingface/diffusers/issues/363). 우리는 이것이 [PyTorch의 `mps` 백엔드](https://github.com/pytorch/pytorch/issues/84039)와 관련이 있다고 생각합니다. 이 문제는 해결되고 있지만 지금은 배치 대신 반복 방법을 사용하는 것이 좋습니다.
|
tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/optimization/onnx.md
ADDED
|
@@ -0,0 +1,65 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2024 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
|
| 14 |
+
# 추론을 위해 ONNX 런타임을 사용하는 방법
|
| 15 |
+
|
| 16 |
+
🤗 Diffusers는 ONNX Runtime과 호환되는 Stable Diffusion 파이프라인을 제공합니다. 이를 통해 ONNX(CPU 포함)를 지원하고 PyTorch의 가속 버전을 사용할 수 없는 모든 하드웨어에서 Stable Diffusion을 실행할 수 있습니다.
|
| 17 |
+
|
| 18 |
+
## 설치
|
| 19 |
+
|
| 20 |
+
다음 명령어로 ONNX Runtime를 지원하는 🤗 Optimum를 설치합니다:
|
| 21 |
+
|
| 22 |
+
```sh
|
| 23 |
+
pip install optimum["onnxruntime"]
|
| 24 |
+
```
|
| 25 |
+
|
| 26 |
+
## Stable Diffusion 추론
|
| 27 |
+
|
| 28 |
+
아래 코드는 ONNX 런타임을 사용하는 방법을 보여줍니다. `StableDiffusionPipeline` 대신 `OnnxStableDiffusionPipeline`을 사용해야 합니다.
|
| 29 |
+
PyTorch 모델을 불러오고 즉시 ONNX 형식으로 변환하려는 경우 `export=True`로 설정합니다.
|
| 30 |
+
|
| 31 |
+
```python
|
| 32 |
+
from optimum.onnxruntime import ORTStableDiffusionPipeline
|
| 33 |
+
|
| 34 |
+
model_id = "stable-diffusion-v1-5/stable-diffusion-v1-5"
|
| 35 |
+
pipe = ORTStableDiffusionPipeline.from_pretrained(model_id, export=True)
|
| 36 |
+
prompt = "a photo of an astronaut riding a horse on mars"
|
| 37 |
+
images = pipe(prompt).images[0]
|
| 38 |
+
pipe.save_pretrained("./onnx-stable-diffusion-v1-5")
|
| 39 |
+
```
|
| 40 |
+
|
| 41 |
+
파이프라인을 ONNX 형식으로 오프라인으로 내보내고 나중에 추론에 사용하려는 경우,
|
| 42 |
+
[`optimum-cli export`](https://huggingface.co/docs/optimum/main/en/exporters/onnx/usage_guides/export_a_model#exporting-a-model-to-onnx-using-the-cli) 명령어를 사용할 수 있습니다:
|
| 43 |
+
|
| 44 |
+
```bash
|
| 45 |
+
optimum-cli export onnx --model stable-diffusion-v1-5/stable-diffusion-v1-5 sd_v15_onnx/
|
| 46 |
+
```
|
| 47 |
+
|
| 48 |
+
그 다음 추론을 수행합니다:
|
| 49 |
+
|
| 50 |
+
```python
|
| 51 |
+
from optimum.onnxruntime import ORTStableDiffusionPipeline
|
| 52 |
+
|
| 53 |
+
model_id = "sd_v15_onnx"
|
| 54 |
+
pipe = ORTStableDiffusionPipeline.from_pretrained(model_id)
|
| 55 |
+
prompt = "a photo of an astronaut riding a horse on mars"
|
| 56 |
+
images = pipe(prompt).images[0]
|
| 57 |
+
```
|
| 58 |
+
|
| 59 |
+
Notice that we didn't have to specify `export=True` above.
|
| 60 |
+
|
| 61 |
+
[Optimum 문서](https://huggingface.co/docs/optimum/)에서 더 많은 예시를 찾을 수 있습니다.
|
| 62 |
+
|
| 63 |
+
## 알려진 이슈들
|
| 64 |
+
|
| 65 |
+
- 여러 프롬프트를 배치로 생성하면 너무 많은 메모리가 사용되는 것 같습니다. 이를 조사하는 동안, 배치 대신 반복 방법이 필요할 수도 있습니다.
|
tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/optimization/open_vino.md
ADDED
|
@@ -0,0 +1,39 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2024 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# 추론을 위한 OpenVINO 사용 방법
|
| 14 |
+
|
| 15 |
+
🤗 [Optimum](https://github.com/huggingface/optimum-intel)은 OpenVINO와 호환되는 Stable Diffusion 파이프라인을 제공합니다.
|
| 16 |
+
이제 다양한 Intel 프로세서에서 OpenVINO Runtime으로 쉽게 추론을 수행할 수 있습니다. ([여기](https://docs.openvino.ai/latest/openvino_docs_OV_UG_supported_plugins_Supported_Devices.html)서 지원되는 전 기기 목록을 확인하세요).
|
| 17 |
+
|
| 18 |
+
## 설치
|
| 19 |
+
|
| 20 |
+
다음 명령어로 🤗 Optimum을 설치합니다:
|
| 21 |
+
|
| 22 |
+
```sh
|
| 23 |
+
pip install optimum["openvino"]
|
| 24 |
+
```
|
| 25 |
+
|
| 26 |
+
## Stable Diffusion 추론
|
| 27 |
+
|
| 28 |
+
OpenVINO 모델을 불러오고 OpenVINO 런타임으로 추론을 실행하려면 `StableDiffusionPipeline`을 `OVStableDiffusionPipeline`으로 교체해야 합니다. PyTorch 모델을 불러오고 즉시 OpenVINO 형식으로 변환하려는 경우 `export=True`로 설정합니다.
|
| 29 |
+
|
| 30 |
+
```python
|
| 31 |
+
from optimum.intel.openvino import OVStableDiffusionPipeline
|
| 32 |
+
|
| 33 |
+
model_id = "stable-diffusion-v1-5/stable-diffusion-v1-5"
|
| 34 |
+
pipe = OVStableDiffusionPipeline.from_pretrained(model_id, export=True)
|
| 35 |
+
prompt = "a photo of an astronaut riding a horse on mars"
|
| 36 |
+
images = pipe(prompt).images[0]
|
| 37 |
+
```
|
| 38 |
+
|
| 39 |
+
[Optimum 문서](https://huggingface.co/docs/optimum/intel/inference#export-and-inference-of-stable-diffusion-models)에서 (정적 reshaping과 모델 컴파일 등의) 더 많은 예시들을 찾을 수 있습니다.
|
tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/optimization/tome.md
ADDED
|
@@ -0,0 +1,121 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2024 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Token Merging (토큰 병합)
|
| 14 |
+
|
| 15 |
+
Token Merging (introduced in [Token Merging: Your ViT But Faster](https://huggingface.co/papers/2210.09461))은 트랜스포머 기반 네트워크의 forward pass에서 중복 토큰이나 패치를 점진적으로 병합하는 방식으로 작동합니다. 이를 통해 기반 네트워크의 추론 지연 시간을 단축할 수 있습니다.
|
| 16 |
+
|
| 17 |
+
Token Merging(ToMe)이 출시된 후, 저자들은 [Fast Stable Diffusion을 위한 토큰 병합](https://huggingface.co/papers/2303.17604)을 발표하여 Stable Diffusion과 더 잘 호환되는 ToMe 버전을 소개했습니다. ToMe를 사용하면 [`DiffusionPipeline`]의 추론 지연 시간을 부드럽게 단축할 수 있습니다. 이 문서에서는 ToMe를 [`StableDiffusionPipeline`]에 적용하는 방법, 예상되는 속도 향상, [`StableDiffusionPipeline`]에서 ToMe를 사용할 때의 질적 측면에 대해 설명합니다.
|
| 18 |
+
|
| 19 |
+
## ToMe 사용하기
|
| 20 |
+
|
| 21 |
+
ToMe의 저자들은 [`tomesd`](https://github.com/dbolya/tomesd)라는 편리한 Python 라이브러리를 공개했는데, 이 라이브러리를 이용하면 [`DiffusionPipeline`]에 ToMe를 다음과 같이 적용할 수 있습니다:
|
| 22 |
+
|
| 23 |
+
```diff
|
| 24 |
+
from diffusers import StableDiffusionPipeline
|
| 25 |
+
import tomesd
|
| 26 |
+
|
| 27 |
+
pipeline = StableDiffusionPipeline.from_pretrained(
|
| 28 |
+
"stable-diffusion-v1-5/stable-diffusion-v1-5", torch_dtype=torch.float16
|
| 29 |
+
).to("cuda")
|
| 30 |
+
+ tomesd.apply_patch(pipeline, ratio=0.5)
|
| 31 |
+
|
| 32 |
+
image = pipeline("a photo of an astronaut riding a horse on mars").images[0]
|
| 33 |
+
```
|
| 34 |
+
|
| 35 |
+
이것이 다입니다!
|
| 36 |
+
|
| 37 |
+
`tomesd.apply_patch()`는 파이프라인 추론 속도와 생성된 토큰의 품질 사이의 균형을 맞출 수 있도록 [여러 개의 인자](https://github.com/dbolya/tomesd#usage)를 노출합니다. 이러한 인수 중 가장 중요한 것은 `ratio(비율)`입니다. `ratio`은 forward pass 중에 병합될 토큰의 수를 제어합니다. `tomesd`에 대한 자세한 내용은 해당 리포지토리(https://github.com/dbolya/tomesd) 및 [논문](https://huggingface.co/papers/2303.17604)을 참고하시기 바랍니다.
|
| 38 |
+
|
| 39 |
+
## `StableDiffusionPipeline`으로 `tomesd` 벤치마킹하기
|
| 40 |
+
|
| 41 |
+
We benchmarked the impact of using `tomesd` on [`StableDiffusionPipeline`] along with [xformers](https://huggingface.co/docs/diffusers/optimization/xformers) across different image resolutions. We used A100 and V100 as our test GPU devices with the following development environment (with Python 3.8.5):
|
| 42 |
+
다양한 이미지 해상도에서 [xformers](https://huggingface.co/docs/diffusers/optimization/xformers)를 적용한 상태에서, [`StableDiffusionPipeline`]에 `tomesd`를 사용했을 때의 영향을 벤치마킹했습니다. 테스트 GPU 장치로 A100과 V100을 사용했으며 개발 환경은 다음과 같습니다(Python 3.8.5 사용):
|
| 43 |
+
|
| 44 |
+
```bash
|
| 45 |
+
- `diffusers` version: 0.15.1
|
| 46 |
+
- Python version: 3.8.16
|
| 47 |
+
- PyTorch version (GPU?): 1.13.1+cu116 (True)
|
| 48 |
+
- Huggingface_hub version: 0.13.2
|
| 49 |
+
- Transformers version: 4.27.2
|
| 50 |
+
- Accelerate version: 0.18.0
|
| 51 |
+
- xFormers version: 0.0.16
|
| 52 |
+
- tomesd version: 0.1.2
|
| 53 |
+
```
|
| 54 |
+
|
| 55 |
+
벤치마킹에는 다음 스크립트를 사용했습니다: [https://gist.github.com/sayakpaul/27aec6bca7eb7b0e0aa4112205850335](https://gist.github.com/sayakpaul/27aec6bca7eb7b0e0aa4112205850335). 결과는 다음과 같습니다:
|
| 56 |
+
|
| 57 |
+
### A100
|
| 58 |
+
|
| 59 |
+
| 해상도 | 배치 크기 | Vanilla | ToMe | ToMe + xFormers | ToMe 속도 향상 (%) | ToMe + xFormers 속도 향상 (%) |
|
| 60 |
+
| --- | --- | --- | --- | --- | --- | --- |
|
| 61 |
+
| 512 | 10 | 6.88 | 5.26 | 4.69 | 23.54651163 | 31.83139535 |
|
| 62 |
+
| | | | | | | |
|
| 63 |
+
| 768 | 10 | OOM | 14.71 | 11 | | |
|
| 64 |
+
| | 8 | OOM | 11.56 | 8.84 | | |
|
| 65 |
+
| | 4 | OOM | 5.98 | 4.66 | | |
|
| 66 |
+
| | 2 | 4.99 | 3.24 | 3.1 | 35.07014028 | 37.8757515 |
|
| 67 |
+
| | 1 | 3.29 | 2.24 | 2.03 | 31.91489362 | 38.29787234 |
|
| 68 |
+
| | | | | | | |
|
| 69 |
+
| 1024 | 10 | OOM | OOM | OOM | | |
|
| 70 |
+
| | 8 | OOM | OOM | OOM | | |
|
| 71 |
+
| | 4 | OOM | 12.51 | 9.09 | | |
|
| 72 |
+
| | 2 | OOM | 6.52 | 4.96 | | |
|
| 73 |
+
| | 1 | 6.4 | 3.61 | 2.81 | 43.59375 | 56.09375 |
|
| 74 |
+
|
| 75 |
+
***결과는 초 단위입니다. 속도 향상은 `Vanilla`과 비교해 계산됩니다.***
|
| 76 |
+
|
| 77 |
+
### V100
|
| 78 |
+
|
| 79 |
+
| 해상도 | 배치 크기 | Vanilla | ToMe | ToMe + xFormers | ToMe 속도 향상 (%) | ToMe + xFormers 속도 향상 (%) |
|
| 80 |
+
| --- | --- | --- | --- | --- | --- | --- |
|
| 81 |
+
| 512 | 10 | OOM | 10.03 | 9.29 | | |
|
| 82 |
+
| | 8 | OOM | 8.05 | 7.47 | | |
|
| 83 |
+
| | 4 | 5.7 | 4.3 | 3.98 | 24.56140351 | 30.1754386 |
|
| 84 |
+
| | 2 | 3.14 | 2.43 | 2.27 | 22.61146497 | 27.70700637 |
|
| 85 |
+
| | 1 | 1.88 | 1.57 | 1.57 | 16.4893617 | 16.4893617 |
|
| 86 |
+
| | | | | | | |
|
| 87 |
+
| 768 | 10 | OOM | OOM | 23.67 | | |
|
| 88 |
+
| | 8 | OOM | OOM | 18.81 | | |
|
| 89 |
+
| | 4 | OOM | 11.81 | 9.7 | | |
|
| 90 |
+
| | 2 | OOM | 6.27 | 5.2 | | |
|
| 91 |
+
| | 1 | 5.43 | 3.38 | 2.82 | 37.75322284 | 48.06629834 |
|
| 92 |
+
| | | | | | | |
|
| 93 |
+
| 1024 | 10 | OOM | OOM | OOM | | |
|
| 94 |
+
| | 8 | OOM | OOM | OOM | | |
|
| 95 |
+
| | 4 | OOM | OOM | 19.35 | | |
|
| 96 |
+
| | 2 | OOM | 13 | 10.78 | | |
|
| 97 |
+
| | 1 | OOM | 6.66 | 5.54 | | |
|
| 98 |
+
|
| 99 |
+
위의 표에서 볼 수 있듯이, 이미지 해상도가 높을수록 `tomesd`를 사용한 속도 향상이 더욱 두드러집니다. 또한 `tomesd`를 사용하면 1024x1024와 같은 더 높은 해상도에서 파이프라인을 실행할 수 있다는 점도 흥미롭습니다.
|
| 100 |
+
|
| 101 |
+
[`torch.compile()`](https://huggingface.co/docs/diffusers/optimization/torch2.0)을 사용하면 추론 속도를 더욱 높일 수 있습니다.
|
| 102 |
+
|
| 103 |
+
## 품질
|
| 104 |
+
|
| 105 |
+
As reported in [the paper](https://huggingface.co/papers/2303.17604), ToMe can preserve the quality of the generated images to a great extent while speeding up inference. By increasing the `ratio`, it is possible to further speed up inference, but that might come at the cost of a deterioration in the image quality.
|
| 106 |
+
|
| 107 |
+
To test the quality of the generated samples using our setup, we sampled a few prompts from the “Parti Prompts” (introduced in [Parti](https://parti.research.google/)) and performed inference with the [`StableDiffusionPipeline`] in the following settings:
|
| 108 |
+
|
| 109 |
+
[논문](https://huggingface.co/papers/2303.17604)에 보고된 바와 같이, ToMe는 생성된 이미지의 품질을 상당 부분 보존하면서 추론 속도를 높일 수 있습니다. `ratio`을 높이면 추론 속도를 더 높일 수 있지만, 이미지 품질이 저하될 수 있습니다.
|
| 110 |
+
|
| 111 |
+
해당 설정을 사용하여 생성된 샘플의 품질을 테스트하기 위해, "Parti 프롬프트"([Parti](https://parti.research.google/)에서 소개)에서 몇 가지 프롬프트를 샘플링하고 다음 설정에서 [`StableDiffusionPipeline`]을 사용하여 추론을 수행했습니다:
|
| 112 |
+
|
| 113 |
+
- Vanilla [`StableDiffusionPipeline`]
|
| 114 |
+
- [`StableDiffusionPipeline`] + ToMe
|
| 115 |
+
- [`StableDiffusionPipeline`] + ToMe + xformers
|
| 116 |
+
|
| 117 |
+
생성된 샘플의 품질이 크게 저하되는 것을 발견하지 못했습니다. 다음은 샘플입니다:
|
| 118 |
+
|
| 119 |
+
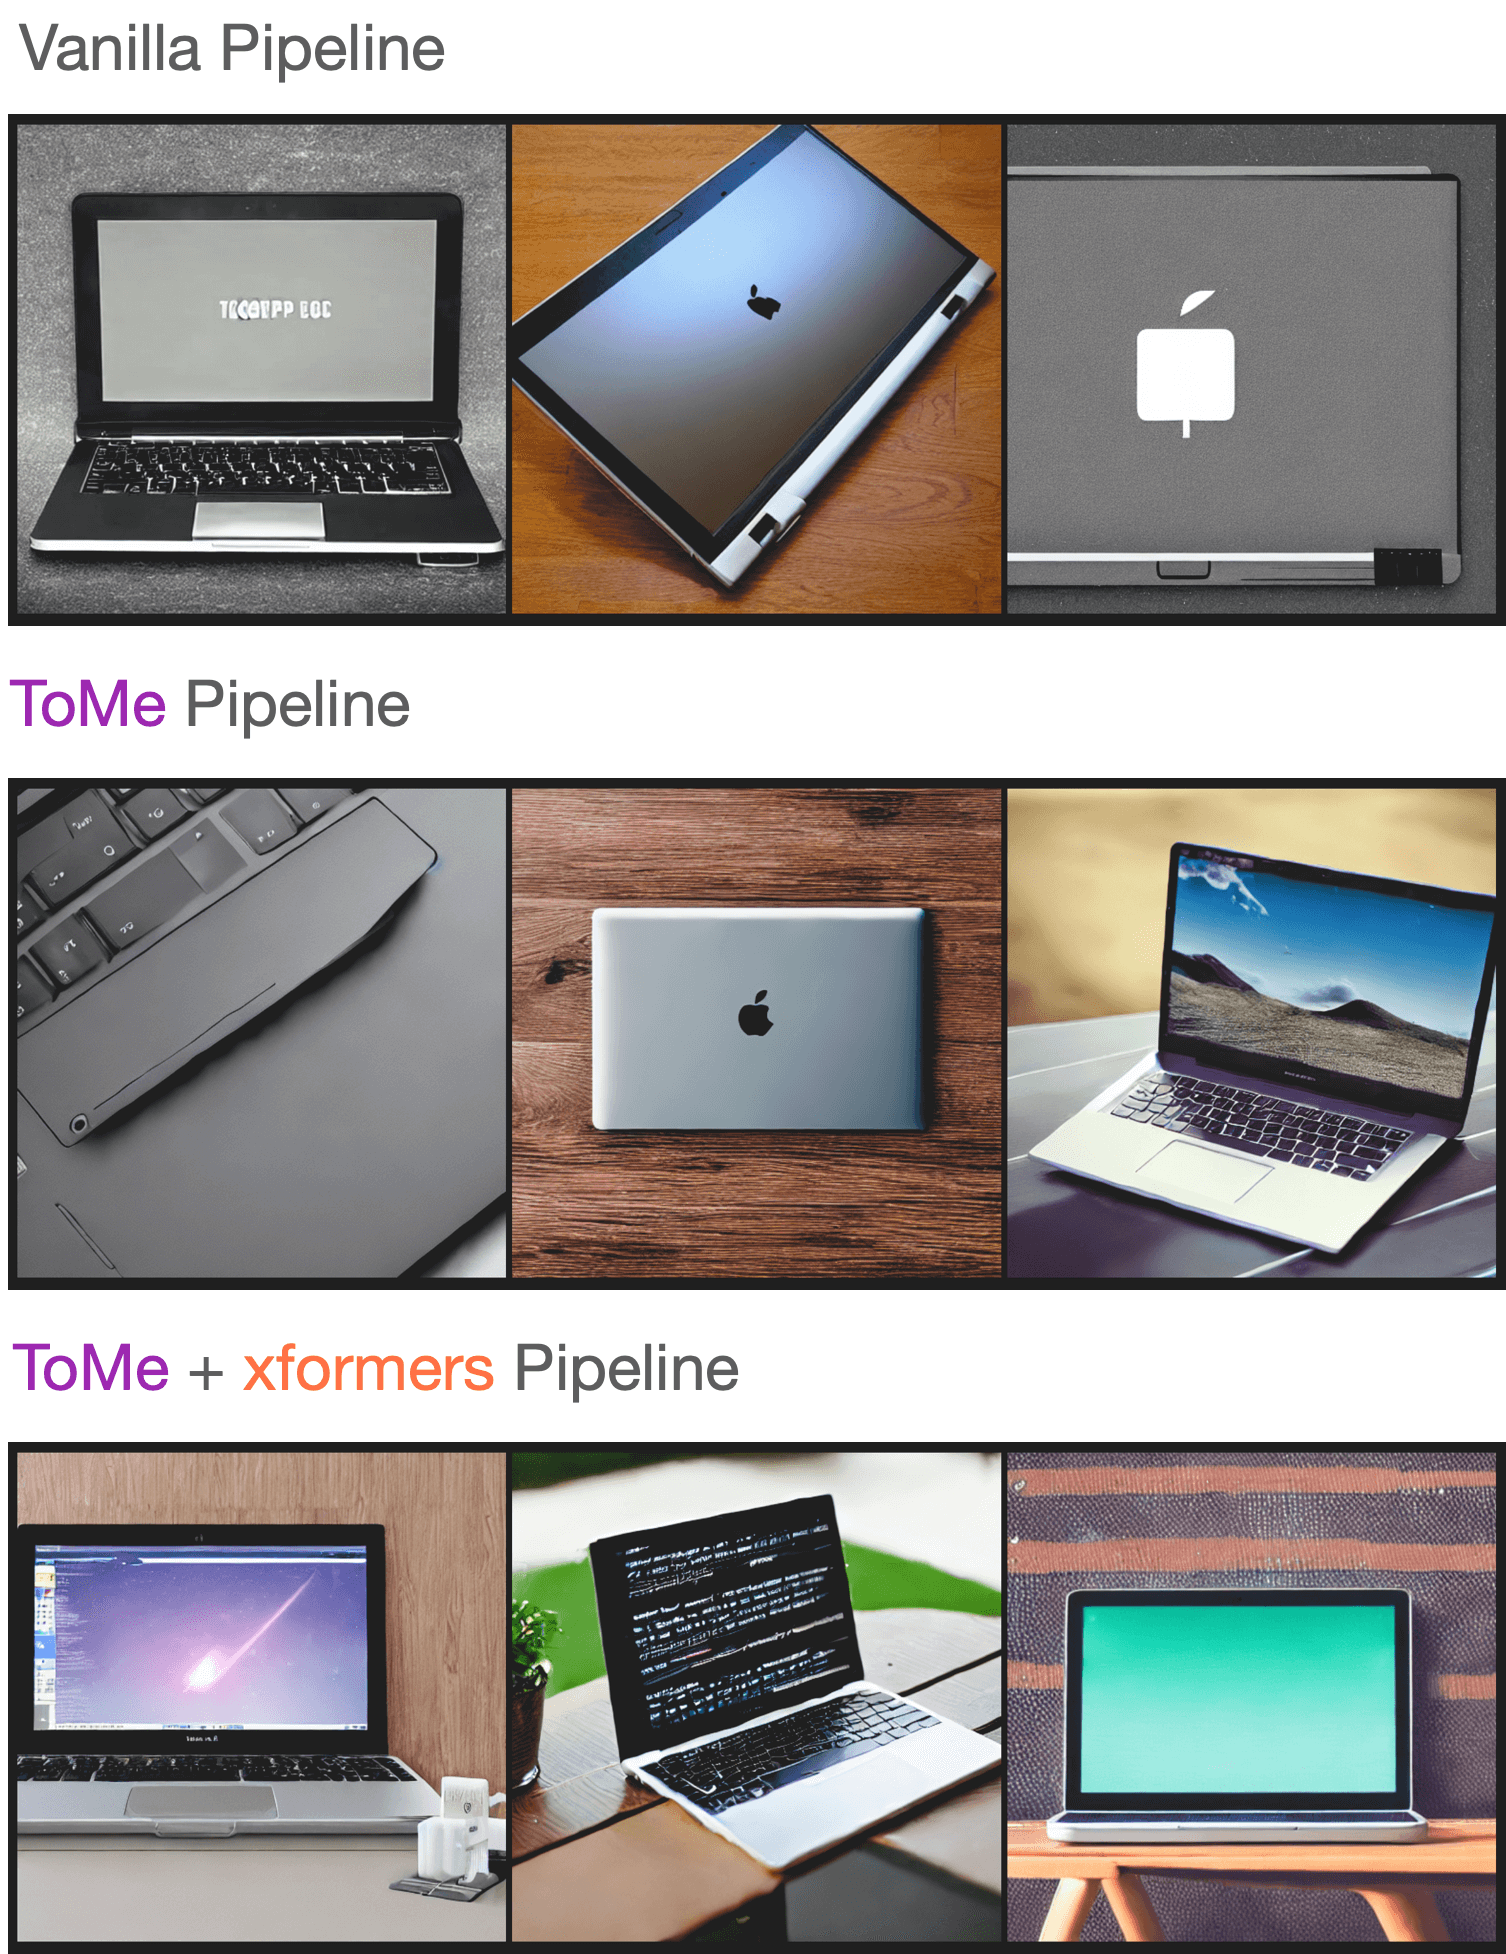
|
| 120 |
+
|
| 121 |
+
생성된 샘플은 [여기](https://wandb.ai/sayakpaul/tomesd-results/runs/23j4bj3i?workspace=)에서 확인할 수 있습니다. 이 실험을 수행하기 위해 [이 스크립트](https://gist.github.com/sayakpaul/8cac98d7f22399085a060992f411ecbd)를 사용했습니다.
|
tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/optimization/torch2.0.md
ADDED
|
@@ -0,0 +1,445 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2024 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Diffusers에서의 PyTorch 2.0 가속화 지원
|
| 14 |
+
|
| 15 |
+
`0.13.0` 버전부터 Diffusers는 [PyTorch 2.0](https://pytorch.org/get-started/pytorch-2.0/)에서의 최신 최적화를 지원합니다. 이는 다음을 포함됩니다.
|
| 16 |
+
1. momory-efficient attention을 사용한 가속화된 트랜스포머 지원 - `xformers`같은 추가적인 dependencies 필요 없음
|
| 17 |
+
2. 추가 성능 향상을 위한 개별 모델에 대한 컴파일 기능 [torch.compile](https://pytorch.org/tutorials/intermediate/torch_compile_tutorial.html) 지원
|
| 18 |
+
|
| 19 |
+
|
| 20 |
+
## 설치
|
| 21 |
+
가속화된 어텐션 구현과 및 `torch.compile()`을 사용하기 위해, pip에서 최신 버전의 PyTorch 2.0을 설치되어 있고 diffusers 0.13.0. 버전 이상인지 확인하세요. 아래 설명된 바와 같이, PyTorch 2.0이 활성화되어 있을 때 diffusers는 최적화된 어텐션 프로세서([`AttnProcessor2_0`](https://github.com/huggingface/diffusers/blob/1a5797c6d4491a879ea5285c4efc377664e0332d/src/diffusers/models/attention_processor.py#L798))를 사용합니다.
|
| 22 |
+
|
| 23 |
+
```bash
|
| 24 |
+
pip install --upgrade torch diffusers
|
| 25 |
+
```
|
| 26 |
+
|
| 27 |
+
## 가속화된 트랜스포머와 `torch.compile` 사용하기.
|
| 28 |
+
|
| 29 |
+
|
| 30 |
+
1. **가속화된 트랜스포머 구현**
|
| 31 |
+
|
| 32 |
+
PyTorch 2.0에는 [`torch.nn.functional.scaled_dot_product_attention`](https://pytorch.org/docs/master/generated/torch.nn.functional.scaled_dot_product_attention) 함수를 통해 최적화된 memory-efficient attention의 구현이 포함되어 있습니다. 이는 입력 및 GPU 유형에 따라 여러 최적화를 자동으로 활성화합니다. 이는 [xFormers](https://github.com/facebookresearch/xformers)의 `memory_efficient_attention`과 유사하지만 기본적으로 PyTorch에 내장되어 있습니다.
|
| 33 |
+
|
| 34 |
+
이러한 최적화는 PyTorch 2.0이 설치되어 있고 `torch.nn.functional.scaled_dot_product_attention`을 사용할 수 있는 경우 Diffusers에서 기본적으로 활성화됩니다. 이를 사용하려면 `torch 2.0`을 설치하고 파이프라인을 사용하기만 하면 됩니다. 예를 들어:
|
| 35 |
+
|
| 36 |
+
```Python
|
| 37 |
+
import torch
|
| 38 |
+
from diffusers import DiffusionPipeline
|
| 39 |
+
|
| 40 |
+
pipe = DiffusionPipeline.from_pretrained("stable-diffusion-v1-5/stable-diffusion-v1-5", torch_dtype=torch.float16)
|
| 41 |
+
pipe = pipe.to("cuda")
|
| 42 |
+
|
| 43 |
+
prompt = "a photo of an astronaut riding a horse on mars"
|
| 44 |
+
image = pipe(prompt).images[0]
|
| 45 |
+
```
|
| 46 |
+
|
| 47 |
+
이를 명시적으로 활성화하려면(필수는 아님) 아래와 같이 수행할 수 있습니다.
|
| 48 |
+
|
| 49 |
+
```diff
|
| 50 |
+
import torch
|
| 51 |
+
from diffusers import DiffusionPipeline
|
| 52 |
+
+ from diffusers.models.attention_processor import AttnProcessor2_0
|
| 53 |
+
|
| 54 |
+
pipe = DiffusionPipeline.from_pretrained("stable-diffusion-v1-5/stable-diffusion-v1-5", torch_dtype=torch.float16).to("cuda")
|
| 55 |
+
+ pipe.unet.set_attn_processor(AttnProcessor2_0())
|
| 56 |
+
|
| 57 |
+
prompt = "a photo of an astronaut riding a horse on mars"
|
| 58 |
+
image = pipe(prompt).images[0]
|
| 59 |
+
```
|
| 60 |
+
|
| 61 |
+
이 실행 과정은 `xFormers`만큼 빠르고 메모리적으로 효율적이어야 합니다. 자세한 내용은 [벤치마크](#benchmark)에서 확인하세요.
|
| 62 |
+
|
| 63 |
+
파이프라인을 보다 deterministic으로 만들거나 파인 튜닝된 모델을 [Core ML](https://huggingface.co/docs/diffusers/v0.16.0/en/optimization/coreml#how-to-run-stable-diffusion-with-core-ml)과 같은 다른 형식으로 변환해야 하는 경우 바닐라 어텐션 프로세서 ([`AttnProcessor`](https://github.com/huggingface/diffusers/blob/1a5797c6d4491a879ea5285c4efc377664e0332d/src/diffusers/models/attention_processor.py#L402))로 되돌릴 수 있습니다. 일반 어텐션 프로세서를 사용하려면 [`~diffusers.UNet2DConditionModel.set_default_attn_processor`] 함수를 사용할 수 있습니다:
|
| 64 |
+
|
| 65 |
+
```Python
|
| 66 |
+
import torch
|
| 67 |
+
from diffusers import DiffusionPipeline
|
| 68 |
+
from diffusers.models.attention_processor import AttnProcessor
|
| 69 |
+
|
| 70 |
+
pipe = DiffusionPipeline.from_pretrained("stable-diffusion-v1-5/stable-diffusion-v1-5", torch_dtype=torch.float16).to("cuda")
|
| 71 |
+
pipe.unet.set_default_attn_processor()
|
| 72 |
+
|
| 73 |
+
prompt = "a photo of an astronaut riding a horse on mars"
|
| 74 |
+
image = pipe(prompt).images[0]
|
| 75 |
+
```
|
| 76 |
+
|
| 77 |
+
2. **torch.compile**
|
| 78 |
+
|
| 79 |
+
추가적인 속도 향상을 위해 새로운 `torch.compile` 기능을 사용할 수 있습니다. 파이프라인의 UNet은 일반적으로 계산 비용이 가장 크기 때문에 나머지 하위 모델(텍스트 인코더와 VAE)은 그대로 두고 `unet`을 `torch.compile`로 래핑합니다. 자세한 내용과 다른 옵션은 [torch 컴파일 문서](https://pytorch.org/tutorials/intermediate/torch_compile_tutorial.html)를 참조하세요.
|
| 80 |
+
|
| 81 |
+
```python
|
| 82 |
+
pipe.unet = torch.compile(pipe.unet, mode="reduce-overhead", fullgraph=True)
|
| 83 |
+
images = pipe(prompt, num_inference_steps=steps, num_images_per_prompt=batch_size).images
|
| 84 |
+
```
|
| 85 |
+
|
| 86 |
+
GPU 유형에 따라 `compile()`은 가속화된 트랜스포머 최적화를 통해 **5% - 300%**의 _추가 성능 향상_을 얻을 수 있습니다. 그러나 컴파일은 Ampere(A100, 3090), Ada(4090) 및 Hopper(H100)와 같은 최신 GPU 아키텍처에서 더 많은 성능 향상을 가져올 수 있음을 참고하세요.
|
| 87 |
+
|
| 88 |
+
컴파일은 완료하는 데 약간의 시간이 걸리므로, 파이프라인을 한 번 준비한 다음 동일한 유형의 추론 작업을 여러 번 수행해야 하는 상황에 가장 적합합니다. 다른 이미지 크기에서 컴파일된 파이프라인을 호출하면 시간적 비용이 많이 들 수 있는 컴파일 작업이 다시 트리거됩니다.
|
| 89 |
+
|
| 90 |
+
|
| 91 |
+
## 벤치마크
|
| 92 |
+
|
| 93 |
+
PyTorch 2.0의 효율적인 어텐션 구현과 `torch.compile`을 사용하여 가장 많이 사용되는 5개의 파이프라인에 대해 다양한 GPU와 배치 크기에 걸쳐 포괄적인 벤치마크를 수행했습니다. 여기서는 [`torch.compile()`이 최적으로 활용되도록 하는](https://github.com/huggingface/diffusers/pull/3313) `diffusers 0.17.0.dev0`을 사용했습니다.
|
| 94 |
+
|
| 95 |
+
### 벤치마킹 코드
|
| 96 |
+
|
| 97 |
+
#### Stable Diffusion text-to-image
|
| 98 |
+
|
| 99 |
+
```python
|
| 100 |
+
from diffusers import DiffusionPipeline
|
| 101 |
+
import torch
|
| 102 |
+
|
| 103 |
+
path = "stable-diffusion-v1-5/stable-diffusion-v1-5"
|
| 104 |
+
|
| 105 |
+
run_compile = True # Set True / False
|
| 106 |
+
|
| 107 |
+
pipe = DiffusionPipeline.from_pretrained(path, torch_dtype=torch.float16)
|
| 108 |
+
pipe = pipe.to("cuda")
|
| 109 |
+
pipe.unet.to(memory_format=torch.channels_last)
|
| 110 |
+
|
| 111 |
+
if run_compile:
|
| 112 |
+
print("Run torch compile")
|
| 113 |
+
pipe.unet = torch.compile(pipe.unet, mode="reduce-overhead", fullgraph=True)
|
| 114 |
+
|
| 115 |
+
prompt = "ghibli style, a fantasy landscape with castles"
|
| 116 |
+
|
| 117 |
+
for _ in range(3):
|
| 118 |
+
images = pipe(prompt=prompt).images
|
| 119 |
+
```
|
| 120 |
+
|
| 121 |
+
#### Stable Diffusion image-to-image
|
| 122 |
+
|
| 123 |
+
```python
|
| 124 |
+
from diffusers import StableDiffusionImg2ImgPipeline
|
| 125 |
+
import requests
|
| 126 |
+
import torch
|
| 127 |
+
from PIL import Image
|
| 128 |
+
from io import BytesIO
|
| 129 |
+
|
| 130 |
+
url = "https://raw.githubusercontent.com/CompVis/stable-diffusion/main/assets/stable-samples/img2img/sketch-mountains-input.jpg"
|
| 131 |
+
|
| 132 |
+
response = requests.get(url)
|
| 133 |
+
init_image = Image.open(BytesIO(response.content)).convert("RGB")
|
| 134 |
+
init_image = init_image.resize((512, 512))
|
| 135 |
+
|
| 136 |
+
path = "stable-diffusion-v1-5/stable-diffusion-v1-5"
|
| 137 |
+
|
| 138 |
+
run_compile = True # Set True / False
|
| 139 |
+
|
| 140 |
+
pipe = StableDiffusionImg2ImgPipeline.from_pretrained(path, torch_dtype=torch.float16)
|
| 141 |
+
pipe = pipe.to("cuda")
|
| 142 |
+
pipe.unet.to(memory_format=torch.channels_last)
|
| 143 |
+
|
| 144 |
+
if run_compile:
|
| 145 |
+
print("Run torch compile")
|
| 146 |
+
pipe.unet = torch.compile(pipe.unet, mode="reduce-overhead", fullgraph=True)
|
| 147 |
+
|
| 148 |
+
prompt = "ghibli style, a fantasy landscape with castles"
|
| 149 |
+
|
| 150 |
+
for _ in range(3):
|
| 151 |
+
image = pipe(prompt=prompt, image=init_image).images[0]
|
| 152 |
+
```
|
| 153 |
+
|
| 154 |
+
#### Stable Diffusion - inpainting
|
| 155 |
+
|
| 156 |
+
```python
|
| 157 |
+
from diffusers import StableDiffusionInpaintPipeline
|
| 158 |
+
import requests
|
| 159 |
+
import torch
|
| 160 |
+
from PIL import Image
|
| 161 |
+
from io import BytesIO
|
| 162 |
+
|
| 163 |
+
url = "https://raw.githubusercontent.com/CompVis/stable-diffusion/main/assets/stable-samples/img2img/sketch-mountains-input.jpg"
|
| 164 |
+
|
| 165 |
+
def download_image(url):
|
| 166 |
+
response = requests.get(url)
|
| 167 |
+
return Image.open(BytesIO(response.content)).convert("RGB")
|
| 168 |
+
|
| 169 |
+
|
| 170 |
+
img_url = "https://raw.githubusercontent.com/CompVis/latent-diffusion/main/data/inpainting_examples/overture-creations-5sI6fQgYIuo.png"
|
| 171 |
+
mask_url = "https://raw.githubusercontent.com/CompVis/latent-diffusion/main/data/inpainting_examples/overture-creations-5sI6fQgYIuo_mask.png"
|
| 172 |
+
|
| 173 |
+
init_image = download_image(img_url).resize((512, 512))
|
| 174 |
+
mask_image = download_image(mask_url).resize((512, 512))
|
| 175 |
+
|
| 176 |
+
path = "runwayml/stable-diffusion-inpainting"
|
| 177 |
+
|
| 178 |
+
run_compile = True # Set True / False
|
| 179 |
+
|
| 180 |
+
pipe = StableDiffusionInpaintPipeline.from_pretrained(path, torch_dtype=torch.float16)
|
| 181 |
+
pipe = pipe.to("cuda")
|
| 182 |
+
pipe.unet.to(memory_format=torch.channels_last)
|
| 183 |
+
|
| 184 |
+
if run_compile:
|
| 185 |
+
print("Run torch compile")
|
| 186 |
+
pipe.unet = torch.compile(pipe.unet, mode="reduce-overhead", fullgraph=True)
|
| 187 |
+
|
| 188 |
+
prompt = "ghibli style, a fantasy landscape with castles"
|
| 189 |
+
|
| 190 |
+
for _ in range(3):
|
| 191 |
+
image = pipe(prompt=prompt, image=init_image, mask_image=mask_image).images[0]
|
| 192 |
+
```
|
| 193 |
+
|
| 194 |
+
#### ControlNet
|
| 195 |
+
|
| 196 |
+
```python
|
| 197 |
+
from diffusers import StableDiffusionControlNetPipeline, ControlNetModel
|
| 198 |
+
import requests
|
| 199 |
+
import torch
|
| 200 |
+
from PIL import Image
|
| 201 |
+
from io import BytesIO
|
| 202 |
+
|
| 203 |
+
url = "https://raw.githubusercontent.com/CompVis/stable-diffusion/main/assets/stable-samples/img2img/sketch-mountains-input.jpg"
|
| 204 |
+
|
| 205 |
+
response = requests.get(url)
|
| 206 |
+
init_image = Image.open(BytesIO(response.content)).convert("RGB")
|
| 207 |
+
init_image = init_image.resize((512, 512))
|
| 208 |
+
|
| 209 |
+
path = "stable-diffusion-v1-5/stable-diffusion-v1-5"
|
| 210 |
+
|
| 211 |
+
run_compile = True # Set True / False
|
| 212 |
+
controlnet = ControlNetModel.from_pretrained("lllyasviel/sd-controlnet-canny", torch_dtype=torch.float16)
|
| 213 |
+
pipe = StableDiffusionControlNetPipeline.from_pretrained(
|
| 214 |
+
path, controlnet=controlnet, torch_dtype=torch.float16
|
| 215 |
+
)
|
| 216 |
+
|
| 217 |
+
pipe = pipe.to("cuda")
|
| 218 |
+
pipe.unet.to(memory_format=torch.channels_last)
|
| 219 |
+
pipe.controlnet.to(memory_format=torch.channels_last)
|
| 220 |
+
|
| 221 |
+
if run_compile:
|
| 222 |
+
print("Run torch compile")
|
| 223 |
+
pipe.unet = torch.compile(pipe.unet, mode="reduce-overhead", fullgraph=True)
|
| 224 |
+
pipe.controlnet = torch.compile(pipe.controlnet, mode="reduce-overhead", fullgraph=True)
|
| 225 |
+
|
| 226 |
+
prompt = "ghibli style, a fantasy landscape with castles"
|
| 227 |
+
|
| 228 |
+
for _ in range(3):
|
| 229 |
+
image = pipe(prompt=prompt, image=init_image).images[0]
|
| 230 |
+
```
|
| 231 |
+
|
| 232 |
+
#### IF text-to-image + upscaling
|
| 233 |
+
|
| 234 |
+
```python
|
| 235 |
+
from diffusers import DiffusionPipeline
|
| 236 |
+
import torch
|
| 237 |
+
|
| 238 |
+
run_compile = True # Set True / False
|
| 239 |
+
|
| 240 |
+
pipe = DiffusionPipeline.from_pretrained("DeepFloyd/IF-I-M-v1.0", variant="fp16", text_encoder=None, torch_dtype=torch.float16)
|
| 241 |
+
pipe.to("cuda")
|
| 242 |
+
pipe_2 = DiffusionPipeline.from_pretrained("DeepFloyd/IF-II-M-v1.0", variant="fp16", text_encoder=None, torch_dtype=torch.float16)
|
| 243 |
+
pipe_2.to("cuda")
|
| 244 |
+
pipe_3 = DiffusionPipeline.from_pretrained("stabilityai/stable-diffusion-x4-upscaler", torch_dtype=torch.float16)
|
| 245 |
+
pipe_3.to("cuda")
|
| 246 |
+
|
| 247 |
+
|
| 248 |
+
pipe.unet.to(memory_format=torch.channels_last)
|
| 249 |
+
pipe_2.unet.to(memory_format=torch.channels_last)
|
| 250 |
+
pipe_3.unet.to(memory_format=torch.channels_last)
|
| 251 |
+
|
| 252 |
+
if run_compile:
|
| 253 |
+
pipe.unet = torch.compile(pipe.unet, mode="reduce-overhead", fullgraph=True)
|
| 254 |
+
pipe_2.unet = torch.compile(pipe_2.unet, mode="reduce-overhead", fullgraph=True)
|
| 255 |
+
pipe_3.unet = torch.compile(pipe_3.unet, mode="reduce-overhead", fullgraph=True)
|
| 256 |
+
|
| 257 |
+
prompt = "the blue hulk"
|
| 258 |
+
|
| 259 |
+
prompt_embeds = torch.randn((1, 2, 4096), dtype=torch.float16)
|
| 260 |
+
neg_prompt_embeds = torch.randn((1, 2, 4096), dtype=torch.float16)
|
| 261 |
+
|
| 262 |
+
for _ in range(3):
|
| 263 |
+
image = pipe(prompt_embeds=prompt_embeds, negative_prompt_embeds=neg_prompt_embeds, output_type="pt").images
|
| 264 |
+
image_2 = pipe_2(image=image, prompt_embeds=prompt_embeds, negative_prompt_embeds=neg_prompt_embeds, output_type="pt").images
|
| 265 |
+
image_3 = pipe_3(prompt=prompt, image=image, noise_level=100).images
|
| 266 |
+
```
|
| 267 |
+
|
| 268 |
+
PyTorch 2.0 및 `torch.compile()`로 얻을 수 있는 가능한 속도 향상에 대해, [Stable Diffusion text-to-image pipeline](StableDiffusionPipeline)에 대한 상대적인 속도 향상을 보여주는 차트를 5개의 서로 다른 GPU 제품군(배치 크기 4)에 대해 나타냅니다:
|
| 269 |
+
|
| 270 |
+
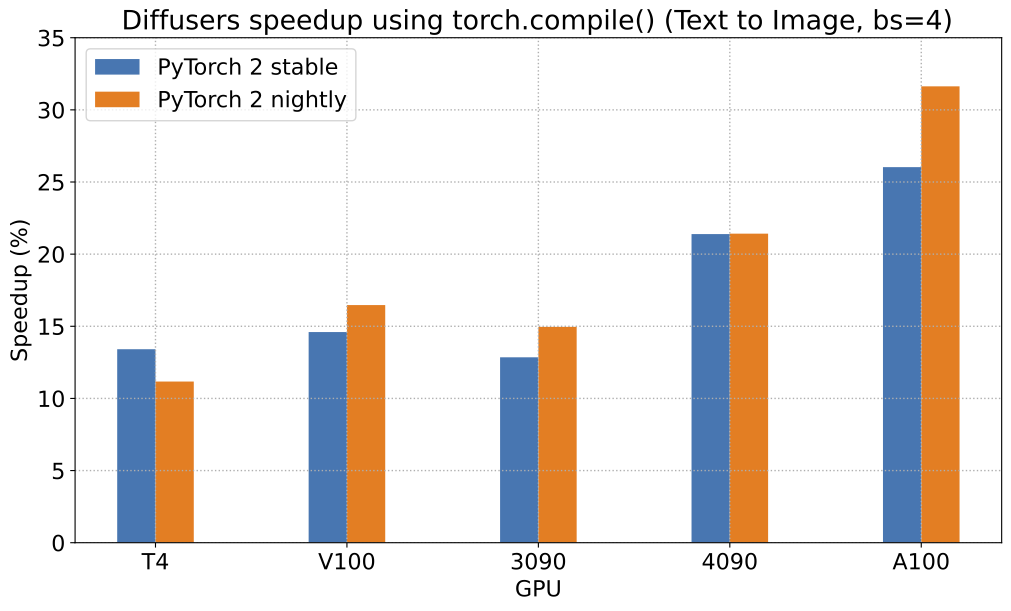
|
| 271 |
+
|
| 272 |
+
To give you an even better idea of how this speed-up holds for the other pipelines presented above, consider the following
|
| 273 |
+
plot that shows the benchmarking numbers from an A100 across three different batch sizes
|
| 274 |
+
(with PyTorch 2.0 nightly and `torch.compile()`):
|
| 275 |
+
이 속도 향상이 위에 제시된 다른 파이프라인에 대해서도 어떻게 유지되는지 더 잘 이해하기 위해, 세 가지의 다른 배치 크기에 걸쳐 A100의 벤치마킹(PyTorch 2.0 nightly 및 `torch.compile() 사용) 수치를 보여주는 차트를 보입니다:
|
| 276 |
+
|
| 277 |
+
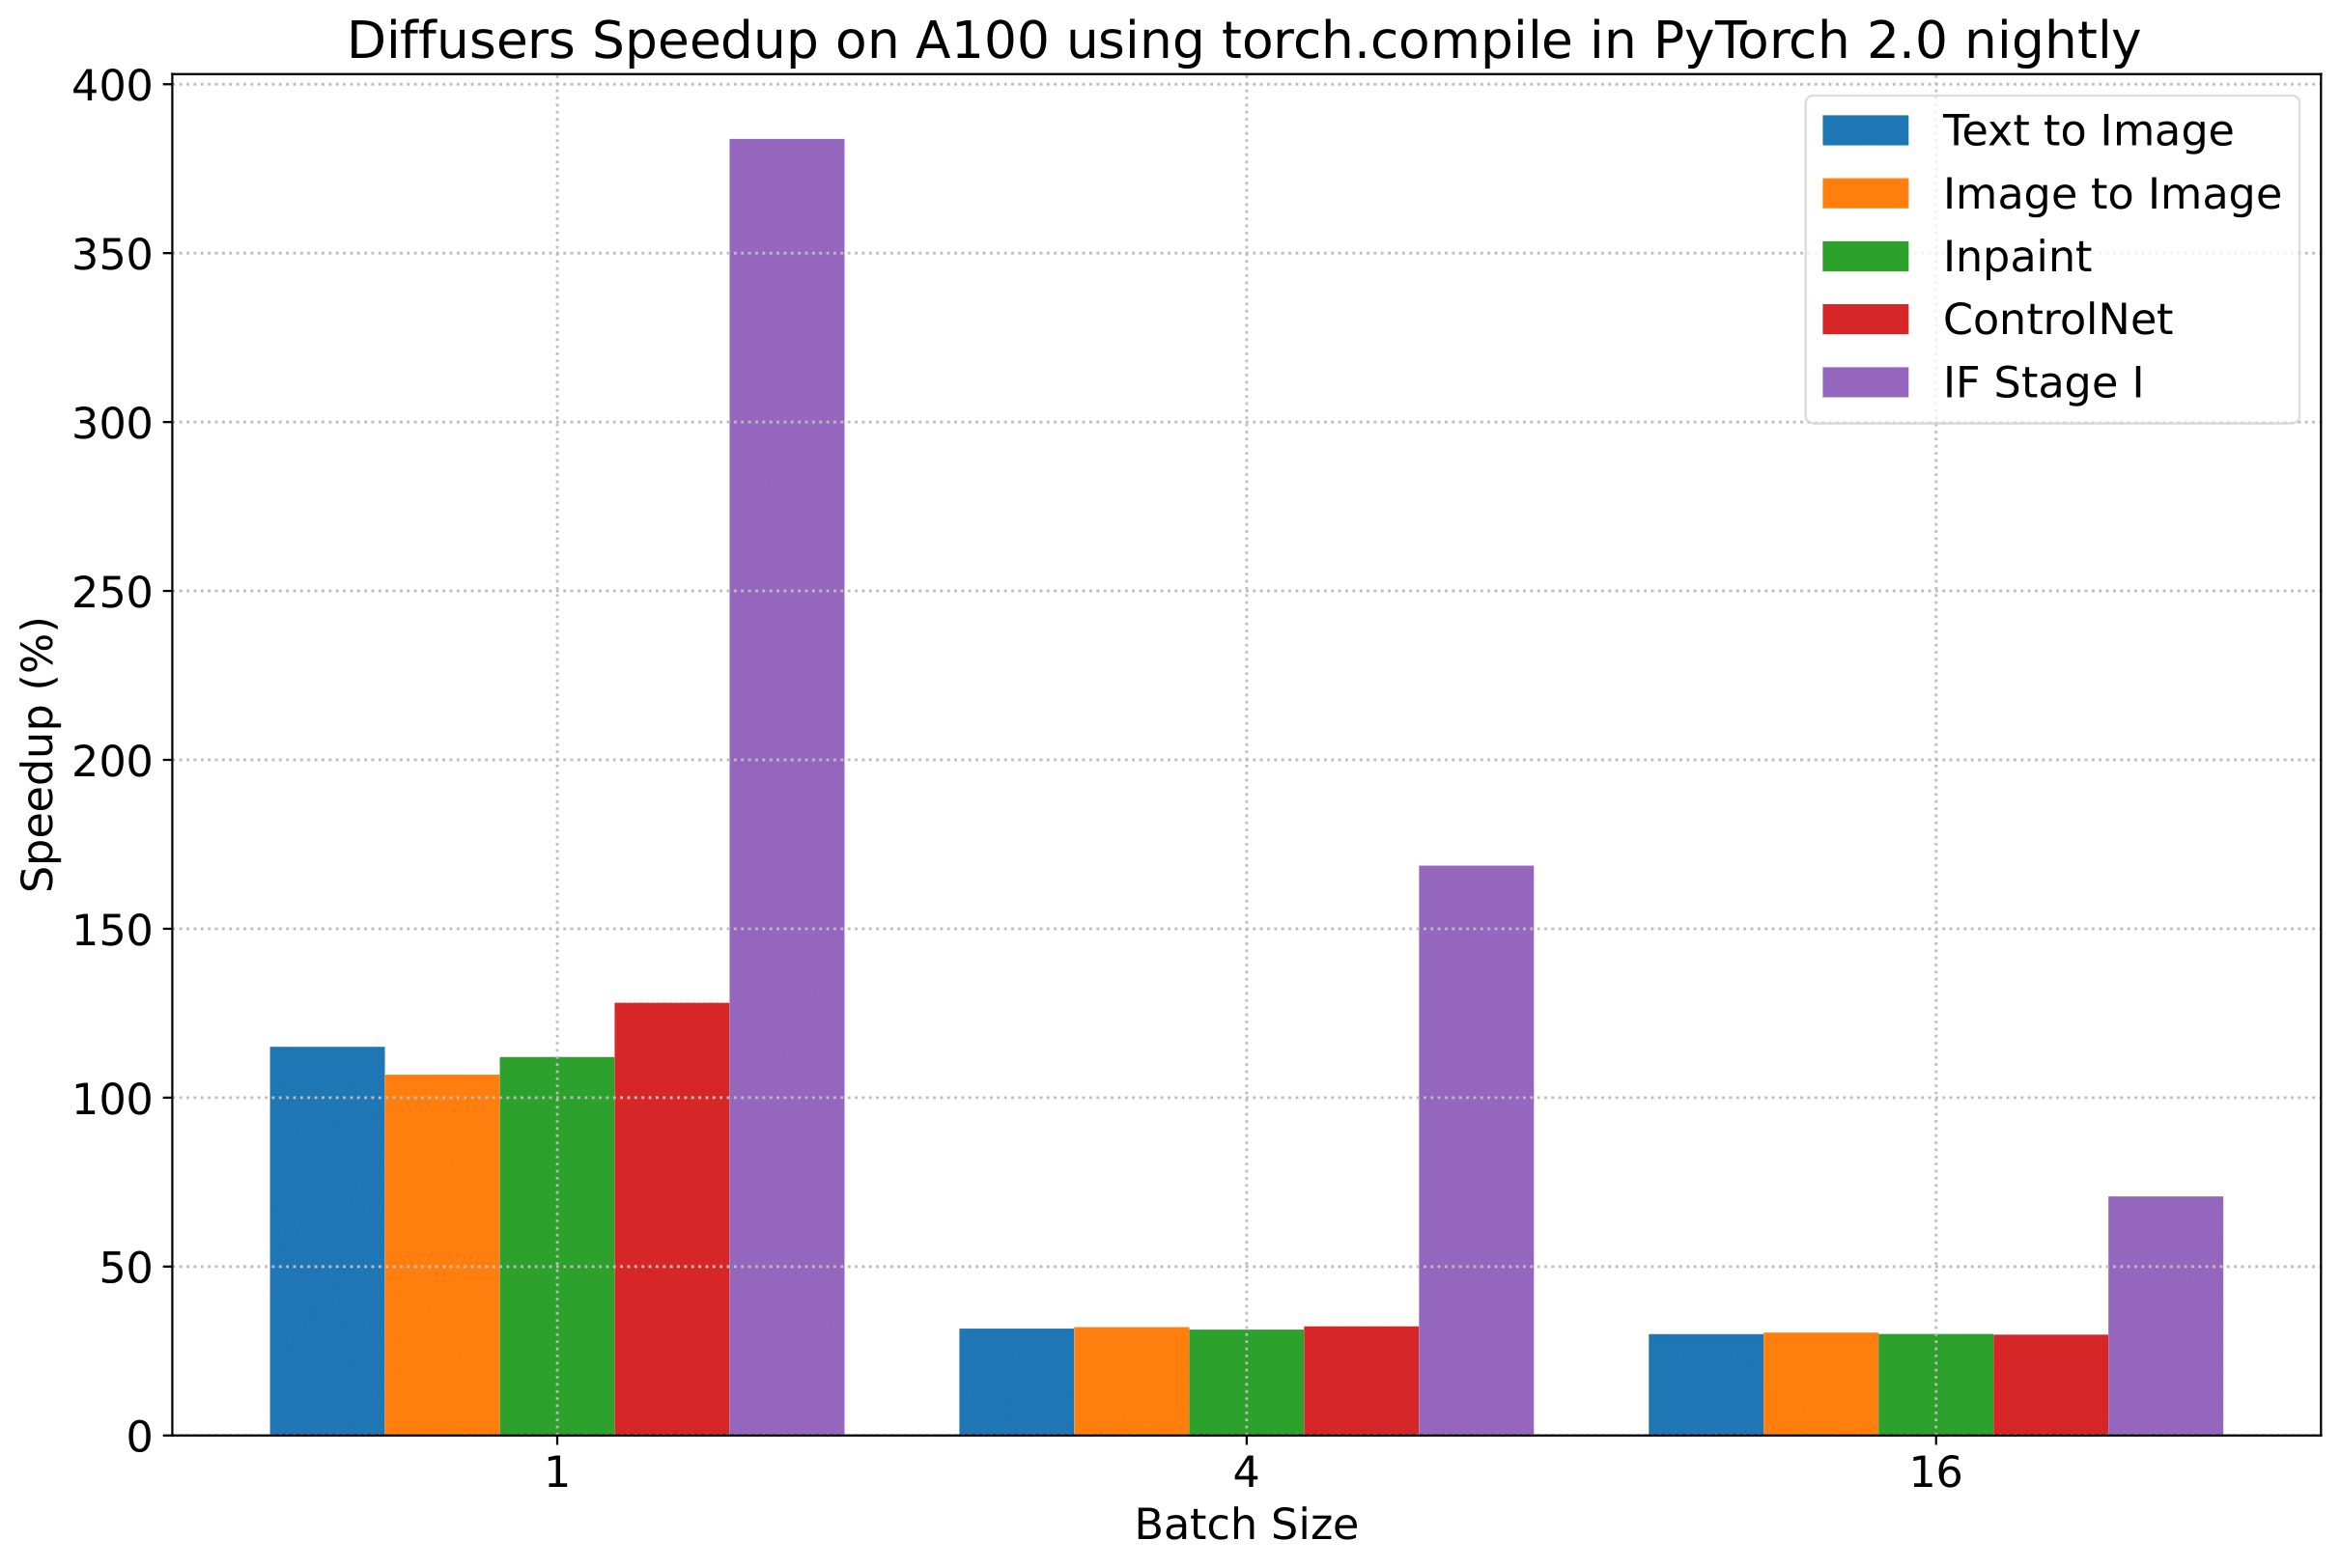
|
| 278 |
+
|
| 279 |
+
_(위 차트의 벤치마크 메트릭은 **초당 iteration 수(iterations/second)**입니다)_
|
| 280 |
+
|
| 281 |
+
그러나 투명성을 위해 모든 벤치마킹 수치를 공개합니다!
|
| 282 |
+
|
| 283 |
+
다음 표들에서는, **_초당 처리되는 iteration_** 수 측면에서의 결과를 보여줍니다.
|
| 284 |
+
|
| 285 |
+
### A100 (batch size: 1)
|
| 286 |
+
|
| 287 |
+
| **Pipeline** | **torch 2.0 - <br>no compile** | **torch nightly - <br>no compile** | **torch 2.0 - <br>compile** | **torch nightly - <br>compile** |
|
| 288 |
+
|:---:|:---:|:---:|:---:|:---:|
|
| 289 |
+
| SD - txt2img | 21.66 | 23.13 | 44.03 | 49.74 |
|
| 290 |
+
| SD - img2img | 21.81 | 22.40 | 43.92 | 46.32 |
|
| 291 |
+
| SD - inpaint | 22.24 | 23.23 | 43.76 | 49.25 |
|
| 292 |
+
| SD - controlnet | 15.02 | 15.82 | 32.13 | 36.08 |
|
| 293 |
+
| IF | 20.21 / <br>13.84 / <br>24.00 | 20.12 / <br>13.70 / <br>24.03 | ❌ | 97.34 / <br>27.23 / <br>111.66 |
|
| 294 |
+
|
| 295 |
+
### A100 (batch size: 4)
|
| 296 |
+
|
| 297 |
+
| **Pipeline** | **torch 2.0 - <br>no compile** | **torch nightly - <br>no compile** | **torch 2.0 - <br>compile** | **torch nightly - <br>compile** |
|
| 298 |
+
|:---:|:---:|:---:|:---:|:---:|
|
| 299 |
+
| SD - txt2img | 11.6 | 13.12 | 14.62 | 17.27 |
|
| 300 |
+
| SD - img2img | 11.47 | 13.06 | 14.66 | 17.25 |
|
| 301 |
+
| SD - inpaint | 11.67 | 13.31 | 14.88 | 17.48 |
|
| 302 |
+
| SD - controlnet | 8.28 | 9.38 | 10.51 | 12.41 |
|
| 303 |
+
| IF | 25.02 | 18.04 | ❌ | 48.47 |
|
| 304 |
+
|
| 305 |
+
### A100 (batch size: 16)
|
| 306 |
+
|
| 307 |
+
| **Pipeline** | **torch 2.0 - <br>no compile** | **torch nightly - <br>no compile** | **torch 2.0 - <br>compile** | **torch nightly - <br>compile** |
|
| 308 |
+
|:---:|:---:|:---:|:---:|:---:|
|
| 309 |
+
| SD - txt2img | 3.04 | 3.6 | 3.83 | 4.68 |
|
| 310 |
+
| SD - img2img | 2.98 | 3.58 | 3.83 | 4.67 |
|
| 311 |
+
| SD - inpaint | 3.04 | 3.66 | 3.9 | 4.76 |
|
| 312 |
+
| SD - controlnet | 2.15 | 2.58 | 2.74 | 3.35 |
|
| 313 |
+
| IF | 8.78 | 9.82 | ❌ | 16.77 |
|
| 314 |
+
|
| 315 |
+
### V100 (batch size: 1)
|
| 316 |
+
|
| 317 |
+
| **Pipeline** | **torch 2.0 - <br>no compile** | **torch nightly - <br>no compile** | **torch 2.0 - <br>compile** | **torch nightly - <br>compile** |
|
| 318 |
+
|:---:|:---:|:---:|:---:|:---:|
|
| 319 |
+
| SD - txt2img | 18.99 | 19.14 | 20.95 | 22.17 |
|
| 320 |
+
| SD - img2img | 18.56 | 19.18 | 20.95 | 22.11 |
|
| 321 |
+
| SD - inpaint | 19.14 | 19.06 | 21.08 | 22.20 |
|
| 322 |
+
| SD - controlnet | 13.48 | 13.93 | 15.18 | 15.88 |
|
| 323 |
+
| IF | 20.01 / <br>9.08 / <br>23.34 | 19.79 / <br>8.98 / <br>24.10 | ❌ | 55.75 / <br>11.57 / <br>57.67 |
|
| 324 |
+
|
| 325 |
+
### V100 (batch size: 4)
|
| 326 |
+
|
| 327 |
+
| **Pipeline** | **torch 2.0 - <br>no compile** | **torch nightly - <br>no compile** | **torch 2.0 - <br>compile** | **torch nightly - <br>compile** |
|
| 328 |
+
|:---:|:---:|:---:|:---:|:---:|
|
| 329 |
+
| SD - txt2img | 5.96 | 5.89 | 6.83 | 6.86 |
|
| 330 |
+
| SD - img2img | 5.90 | 5.91 | 6.81 | 6.82 |
|
| 331 |
+
| SD - inpaint | 5.99 | 6.03 | 6.93 | 6.95 |
|
| 332 |
+
| SD - controlnet | 4.26 | 4.29 | 4.92 | 4.93 |
|
| 333 |
+
| IF | 15.41 | 14.76 | ❌ | 22.95 |
|
| 334 |
+
|
| 335 |
+
### V100 (batch size: 16)
|
| 336 |
+
|
| 337 |
+
| **Pipeline** | **torch 2.0 - <br>no compile** | **torch nightly - <br>no compile** | **torch 2.0 - <br>compile** | **torch nightly - <br>compile** |
|
| 338 |
+
|:---:|:---:|:---:|:---:|:---:|
|
| 339 |
+
| SD - txt2img | 1.66 | 1.66 | 1.92 | 1.90 |
|
| 340 |
+
| SD - img2img | 1.65 | 1.65 | 1.91 | 1.89 |
|
| 341 |
+
| SD - inpaint | 1.69 | 1.69 | 1.95 | 1.93 |
|
| 342 |
+
| SD - controlnet | 1.19 | 1.19 | OOM after warmup | 1.36 |
|
| 343 |
+
| IF | 5.43 | 5.29 | ❌ | 7.06 |
|
| 344 |
+
|
| 345 |
+
### T4 (batch size: 1)
|
| 346 |
+
|
| 347 |
+
| **Pipeline** | **torch 2.0 - <br>no compile** | **torch nightly - <br>no compile** | **torch 2.0 - <br>compile** | **torch nightly - <br>compile** |
|
| 348 |
+
|:---:|:---:|:---:|:---:|:---:|
|
| 349 |
+
| SD - txt2img | 6.9 | 6.95 | 7.3 | 7.56 |
|
| 350 |
+
| SD - img2img | 6.84 | 6.99 | 7.04 | 7.55 |
|
| 351 |
+
| SD - inpaint | 6.91 | 6.7 | 7.01 | 7.37 |
|
| 352 |
+
| SD - controlnet | 4.89 | 4.86 | 5.35 | 5.48 |
|
| 353 |
+
| IF | 17.42 / <br>2.47 / <br>18.52 | 16.96 / <br>2.45 / <br>18.69 | ❌ | 24.63 / <br>2.47 / <br>23.39 |
|
| 354 |
+
|
| 355 |
+
### T4 (batch size: 4)
|
| 356 |
+
|
| 357 |
+
| **Pipeline** | **torch 2.0 - <br>no compile** | **torch nightly - <br>no compile** | **torch 2.0 - <br>compile** | **torch nightly - <br>compile** |
|
| 358 |
+
|:---:|:---:|:---:|:---:|:---:|
|
| 359 |
+
| SD - txt2img | 1.79 | 1.79 | 2.03 | 1.99 |
|
| 360 |
+
| SD - img2img | 1.77 | 1.77 | 2.05 | 2.04 |
|
| 361 |
+
| SD - inpaint | 1.81 | 1.82 | 2.09 | 2.09 |
|
| 362 |
+
| SD - controlnet | 1.34 | 1.27 | 1.47 | 1.46 |
|
| 363 |
+
| IF | 5.79 | 5.61 | ❌ | 7.39 |
|
| 364 |
+
|
| 365 |
+
### T4 (batch size: 16)
|
| 366 |
+
|
| 367 |
+
| **Pipeline** | **torch 2.0 - <br>no compile** | **torch nightly - <br>no compile** | **torch 2.0 - <br>compile** | **torch nightly - <br>compile** |
|
| 368 |
+
|:---:|:---:|:---:|:---:|:---:|
|
| 369 |
+
| SD - txt2img | 2.34s | 2.30s | OOM after 2nd iteration | 1.99s |
|
| 370 |
+
| SD - img2img | 2.35s | 2.31s | OOM after warmup | 2.00s |
|
| 371 |
+
| SD - inpaint | 2.30s | 2.26s | OOM after 2nd iteration | 1.95s |
|
| 372 |
+
| SD - controlnet | OOM after 2nd iteration | OOM after 2nd iteration | OOM after warmup | OOM after warmup |
|
| 373 |
+
| IF * | 1.44 | 1.44 | ❌ | 1.94 |
|
| 374 |
+
|
| 375 |
+
### RTX 3090 (batch size: 1)
|
| 376 |
+
|
| 377 |
+
| **Pipeline** | **torch 2.0 - <br>no compile** | **torch nightly - <br>no compile** | **torch 2.0 - <br>compile** | **torch nightly - <br>compile** |
|
| 378 |
+
|:---:|:---:|:---:|:---:|:---:|
|
| 379 |
+
| SD - txt2img | 22.56 | 22.84 | 23.84 | 25.69 |
|
| 380 |
+
| SD - img2img | 22.25 | 22.61 | 24.1 | 25.83 |
|
| 381 |
+
| SD - inpaint | 22.22 | 22.54 | 24.26 | 26.02 |
|
| 382 |
+
| SD - controlnet | 16.03 | 16.33 | 17.38 | 18.56 |
|
| 383 |
+
| IF | 27.08 / <br>9.07 / <br>31.23 | 26.75 / <br>8.92 / <br>31.47 | ❌ | 68.08 / <br>11.16 / <br>65.29 |
|
| 384 |
+
|
| 385 |
+
### RTX 3090 (batch size: 4)
|
| 386 |
+
|
| 387 |
+
| **Pipeline** | **torch 2.0 - <br>no compile** | **torch nightly - <br>no compile** | **torch 2.0 - <br>compile** | **torch nightly - <br>compile** |
|
| 388 |
+
|:---:|:---:|:---:|:---:|:---:|
|
| 389 |
+
| SD - txt2img | 6.46 | 6.35 | 7.29 | 7.3 |
|
| 390 |
+
| SD - img2img | 6.33 | 6.27 | 7.31 | 7.26 |
|
| 391 |
+
| SD - inpaint | 6.47 | 6.4 | 7.44 | 7.39 |
|
| 392 |
+
| SD - controlnet | 4.59 | 4.54 | 5.27 | 5.26 |
|
| 393 |
+
| IF | 16.81 | 16.62 | ❌ | 21.57 |
|
| 394 |
+
|
| 395 |
+
### RTX 3090 (batch size: 16)
|
| 396 |
+
|
| 397 |
+
| **Pipeline** | **torch 2.0 - <br>no compile** | **torch nightly - <br>no compile** | **torch 2.0 - <br>compile** | **torch nightly - <br>compile** |
|
| 398 |
+
|:---:|:---:|:---:|:---:|:---:|
|
| 399 |
+
| SD - txt2img | 1.7 | 1.69 | 1.93 | 1.91 |
|
| 400 |
+
| SD - img2img | 1.68 | 1.67 | 1.93 | 1.9 |
|
| 401 |
+
| SD - inpaint | 1.72 | 1.71 | 1.97 | 1.94 |
|
| 402 |
+
| SD - controlnet | 1.23 | 1.22 | 1.4 | 1.38 |
|
| 403 |
+
| IF | 5.01 | 5.00 | ❌ | 6.33 |
|
| 404 |
+
|
| 405 |
+
### RTX 4090 (batch size: 1)
|
| 406 |
+
|
| 407 |
+
| **Pipeline** | **torch 2.0 - <br>no compile** | **torch nightly - <br>no compile** | **torch 2.0 - <br>compile** | **torch nightly - <br>compile** |
|
| 408 |
+
|:---:|:---:|:---:|:---:|:---:|
|
| 409 |
+
| SD - txt2img | 40.5 | 41.89 | 44.65 | 49.81 |
|
| 410 |
+
| SD - img2img | 40.39 | 41.95 | 44.46 | 49.8 |
|
| 411 |
+
| SD - inpaint | 40.51 | 41.88 | 44.58 | 49.72 |
|
| 412 |
+
| SD - controlnet | 29.27 | 30.29 | 32.26 | 36.03 |
|
| 413 |
+
| IF | 69.71 / <br>18.78 / <br>85.49 | 69.13 / <br>18.80 / <br>85.56 | ❌ | 124.60 / <br>26.37 / <br>138.79 |
|
| 414 |
+
|
| 415 |
+
### RTX 4090 (batch size: 4)
|
| 416 |
+
|
| 417 |
+
| **Pipeline** | **torch 2.0 - <br>no compile** | **torch nightly - <br>no compile** | **torch 2.0 - <br>compile** | **torch nightly - <br>compile** |
|
| 418 |
+
|:---:|:---:|:---:|:---:|:---:|
|
| 419 |
+
| SD - txt2img | 12.62 | 12.84 | 15.32 | 15.59 |
|
| 420 |
+
| SD - img2img | 12.61 | 12,.79 | 15.35 | 15.66 |
|
| 421 |
+
| SD - inpaint | 12.65 | 12.81 | 15.3 | 15.58 |
|
| 422 |
+
| SD - controlnet | 9.1 | 9.25 | 11.03 | 11.22 |
|
| 423 |
+
| IF | 31.88 | 31.14 | ❌ | 43.92 |
|
| 424 |
+
|
| 425 |
+
### RTX 4090 (batch size: 16)
|
| 426 |
+
|
| 427 |
+
| **Pipeline** | **torch 2.0 - <br>no compile** | **torch nightly - <br>no compile** | **torch 2.0 - <br>compile** | **torch nightly - <br>compile** |
|
| 428 |
+
|:---:|:---:|:---:|:---:|:---:|
|
| 429 |
+
| SD - txt2img | 3.17 | 3.2 | 3.84 | 3.85 |
|
| 430 |
+
| SD - img2img | 3.16 | 3.2 | 3.84 | 3.85 |
|
| 431 |
+
| SD - inpaint | 3.17 | 3.2 | 3.85 | 3.85 |
|
| 432 |
+
| SD - controlnet | 2.23 | 2.3 | 2.7 | 2.75 |
|
| 433 |
+
| IF | 9.26 | 9.2 | ❌ | 13.31 |
|
| 434 |
+
|
| 435 |
+
## 참고
|
| 436 |
+
|
| 437 |
+
* Follow [this PR](https://github.com/huggingface/diffusers/pull/3313) for more details on the environment used for conducting the benchmarks.
|
| 438 |
+
* For the IF pipeline and batch sizes > 1, we only used a batch size of >1 in the first IF pipeline for text-to-image generation and NOT for upscaling. So, that means the two upscaling pipelines received a batch size of 1.
|
| 439 |
+
|
| 440 |
+
*Thanks to [Horace He](https://github.com/Chillee) from the PyTorch team for their support in improving our support of `torch.compile()` in Diffusers.*
|
| 441 |
+
|
| 442 |
+
* 벤치마크 수행에 사용된 환경에 대한 자세한 내용은 [이 PR](https://github.com/huggingface/diffusers/pull/3313)을 참조하세요.
|
| 443 |
+
* IF 파이프라인와 배치 크기 > 1의 경우 첫 번째 IF 파이프라인에서 text-to-image 생성을 위한 배치 크기 > 1만 사용했으며 업스케일링에는 사용하지 않았습니다. 즉, 두 개의 업스케일링 파이프라인이 배치 크기 1임을 의미합니다.
|
| 444 |
+
|
| 445 |
+
*Diffusers에서 `torch.compile()` 지원을 개선하는 데 도움을 준 PyTorch 팀의 [Horace He](https://github.com/Chillee)에게 감사드립니다.*
|
tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/optimization/xformers.md
ADDED
|
@@ -0,0 +1,36 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2024 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# xFormers 설치하기
|
| 14 |
+
|
| 15 |
+
추론과 학습 모두에 [xFormers](https://github.com/facebookresearch/xformers)를 사용하는 것이 좋습니다.
|
| 16 |
+
자체 테스트로 어텐션 블록에서 수행된 최적화가 더 빠른 속도와 적은 메모리 소비를 확인했습니다.
|
| 17 |
+
|
| 18 |
+
2023년 1월에 출시된 xFormers 버전 '0.0.16'부터 사전 빌드된 pip wheel을 사용하여 쉽게 설치할 수 있습니다:
|
| 19 |
+
|
| 20 |
+
```bash
|
| 21 |
+
pip install xformers
|
| 22 |
+
```
|
| 23 |
+
|
| 24 |
+
<Tip>
|
| 25 |
+
|
| 26 |
+
xFormers PIP 패키지에는 최신 버전의 PyTorch(xFormers 0.0.16에 1.13.1)가 필요합니다. 이전 버전의 PyTorch를 사용해야 하는 경우 [프로젝트 지침](https://github.com/facebookresearch/xformers#installing-xformers)의 소스를 사용해 xFormers를 설치하는 것이 좋습니다.
|
| 27 |
+
|
| 28 |
+
</Tip>
|
| 29 |
+
|
| 30 |
+
xFormers를 설치하면, [여기](fp16#memory-efficient-attention)서 설명한 것처럼 'enable_xformers_memory_efficient_attention()'을 사용하여 추론 속도를 높이고 메모리 소비를 줄일 수 있습니다.
|
| 31 |
+
|
| 32 |
+
<Tip warning={true}>
|
| 33 |
+
|
| 34 |
+
[이 이슈](https://github.com/huggingface/diffusers/issues/2234#issuecomment-1416931212)에 따르면 xFormers `v0.0.16`에서 GPU를 사용한 학습(파인 튜닝 또는 Dreambooth)을 할 수 없습니다. 해당 문제가 발견되면. 해당 코멘트를 참고해 development 버전을 설치하세요.
|
| 35 |
+
|
| 36 |
+
</Tip>
|
tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/quicktour.md
ADDED
|
@@ -0,0 +1,313 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2024 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
[[open-in-colab]]
|
| 13 |
+
|
| 14 |
+
# 훑어보기
|
| 15 |
+
|
| 16 |
+
Diffusion 모델은 이미지나 오디오와 같은 관심 샘플들을 생성하기 위해 랜덤 가우시안 노이즈를 단계별로 제거하도록 학습됩니다. 이로 인해 생성 AI에 대한 관심이 매우 높아졌으며, 인터넷에서 diffusion 생성 이미지의 예를 본 적이 있을 것입니다. 🧨 Diffusers는 누구나 diffusion 모델들을 널리 이용할 수 있도록 하기 위한 라이브러리입니다.
|
| 17 |
+
|
| 18 |
+
개발자든 일반 사용자든 이 훑어보기를 통해 🧨 Diffusers를 소개하고 빠르게 생성할 수 있도록 도와드립니다! 알아야 할 라이브러리의 주요 구성 요소는 크게 세 가지입니다:
|
| 19 |
+
|
| 20 |
+
* [`DiffusionPipeline`]은 추론을 위해 사전 학습된 diffusion 모델에서 샘플을 빠르게 생성하도록 설계된 높은 수준의 엔드투엔드 클래스입니다.
|
| 21 |
+
* Diffusion 시스템 생성을 위한 빌딩 블록으로 사용할 수 있는 널리 사용되는 사전 학습된 [model](./api/models) 아키텍처 및 모듈.
|
| 22 |
+
* 다양한 [schedulers](./api/schedulers/overview) - 학습을 위해 노이즈를 추가하는 방법과 추론 중에 노이즈 제거된 이미지를 생성하는 방법을 제어하는 알고리즘입니다.
|
| 23 |
+
|
| 24 |
+
훑어보기에서는 추론을 위해 [`DiffusionPipeline`]을 사용하는 방법을 보여준 다음, 모델과 스케줄러를 결합하여 [`DiffusionPipeline`] 내부에서 일어나는 일을 복제하는 방법을 안내합니다.
|
| 25 |
+
|
| 26 |
+
<Tip>
|
| 27 |
+
|
| 28 |
+
훑어보기는 간결한 버전의 🧨 Diffusers 소개로서 [노트북](https://colab.research.google.com/github/huggingface/notebooks/blob/main/diffusers/diffusers_intro.ipynb) 빠르게 시작할 수 있도록 도와드립니다. 디퓨저의 목표, 디자인 철학, 핵심 API에 대한 추가 세부 정보를 자세히 알아보려면 노트북을 확인하세요!
|
| 29 |
+
|
| 30 |
+
</Tip>
|
| 31 |
+
|
| 32 |
+
시작하기 전에 필요한 라이브러리가 모두 설치되어 있는지 확인하세요:
|
| 33 |
+
|
| 34 |
+
```py
|
| 35 |
+
# 주석 풀어서 Colab에 필요한 라이브러리 설치하기.
|
| 36 |
+
#!pip install --upgrade diffusers accelerate transformers
|
| 37 |
+
```
|
| 38 |
+
|
| 39 |
+
- [🤗 Accelerate](https://huggingface.co/docs/accelerate/index)는 추론 및 학습을 위한 모델 로딩 속도를 높여줍니다.
|
| 40 |
+
- [🤗 Transformers](https://huggingface.co/docs/transformers/index)는 [Stable Diffusion](https://huggingface.co/docs/diffusers/api/pipelines/stable_diffusion/overview)과 같이 가장 많이 사용되는 diffusion 모델을 실행하는 데 필요합니다.
|
| 41 |
+
|
| 42 |
+
## DiffusionPipeline
|
| 43 |
+
|
| 44 |
+
[`DiffusionPipeline`] 은 추론을 위해 사전 학습된 diffusion 시스템을 사용하는 가장 쉬운 방법입니다. 모델과 스케줄러를 포함하는 엔드 투 엔드 시스템입니다. 다양한 작업에 [`DiffusionPipeline`]을 바로 사용할 수 있습니다. 아래 표에서 지원되는 몇 가지 작업을 살펴보고, 지원되는 작업의 전체 목록은 [🧨 Diffusers Summary](./api/pipelines/overview#diffusers-summary) 표에서 확인할 수 있습니다.
|
| 45 |
+
|
| 46 |
+
| **Task** | **Description** | **Pipeline**
|
| 47 |
+
|------------------------------|--------------------------------------------------------------------------------------------------------------|-----------------|
|
| 48 |
+
| Unconditional Image Generation | generate an image from Gaussian noise | [unconditional_image_generation](./using-diffusers/unconditional_image_generation) |
|
| 49 |
+
| Text-Guided Image Generation | generate an image given a text prompt | [conditional_image_generation](./using-diffusers/conditional_image_generation) |
|
| 50 |
+
| Text-Guided Image-to-Image Translation | adapt an image guided by a text prompt | [img2img](./using-diffusers/img2img) |
|
| 51 |
+
| Text-Guided Image-Inpainting | fill the masked part of an image given the image, the mask and a text prompt | [inpaint](./using-diffusers/inpaint) |
|
| 52 |
+
| Text-Guided Depth-to-Image Translation | adapt parts of an image guided by a text prompt while preserving structure via depth estimation | [depth2img](./using-diffusers/depth2img) |
|
| 53 |
+
|
| 54 |
+
먼저 [`DiffusionPipeline`]의 인스턴스를 생성하고 다운로드할 파이프라인 체크포인트를 지정합니다.
|
| 55 |
+
허깅페이스 허브에 저장된 모든 [checkpoint](https://huggingface.co/models?library=diffusers&sort=downloads)에 대해 [`DiffusionPipeline`]을 ���용할 수 있습니다.
|
| 56 |
+
이 훑어보기에서는 text-to-image 생성을 위한 [`stable-diffusion-v1-5`](https://huggingface.co/stable-diffusion-v1-5/stable-diffusion-v1-5) 체크포인트를 로드합니다.
|
| 57 |
+
|
| 58 |
+
<Tip warning={true}>
|
| 59 |
+
|
| 60 |
+
[Stable Diffusion](https://huggingface.co/CompVis/stable-diffusion) 모델의 경우, 모델을 실행하기 전에 [라이선스](https://huggingface.co/spaces/CompVis/stable-diffusion-license)를 먼저 주의 깊게 읽어주세요. 🧨 Diffusers는 불쾌하거나 유해한 콘텐츠를 방지하기 위해 [`safety_checker`](https://github.com/huggingface/diffusers/blob/main/src/diffusers/pipelines/stable_diffusion/safety_checker.py)를 구현하고 있지만, 모델의 향상된 이미지 생성 기능으로 인해 여전히 잠재적으로 유해한 콘텐츠가 생성될 수 있습니다.
|
| 61 |
+
|
| 62 |
+
</Tip>
|
| 63 |
+
|
| 64 |
+
[`~DiffusionPipeline.from_pretrained`] 방법으로 모델 로드하기:
|
| 65 |
+
|
| 66 |
+
```python
|
| 67 |
+
>>> from diffusers import DiffusionPipeline
|
| 68 |
+
|
| 69 |
+
>>> pipeline = DiffusionPipeline.from_pretrained("stable-diffusion-v1-5/stable-diffusion-v1-5")
|
| 70 |
+
```
|
| 71 |
+
|
| 72 |
+
The [`DiffusionPipeline`]은 모든 모델링, 토큰화, 스케줄링 컴포넌트를 다운로드하고 캐시합니다. Stable Diffusion Pipeline은 무엇보다도 [`UNet2DConditionModel`]과 [`PNDMScheduler`]로 구성되어 있음을 알 수 있습니다:
|
| 73 |
+
|
| 74 |
+
```py
|
| 75 |
+
>>> pipeline
|
| 76 |
+
StableDiffusionPipeline {
|
| 77 |
+
"_class_name": "StableDiffusionPipeline",
|
| 78 |
+
"_diffusers_version": "0.13.1",
|
| 79 |
+
...,
|
| 80 |
+
"scheduler": [
|
| 81 |
+
"diffusers",
|
| 82 |
+
"PNDMScheduler"
|
| 83 |
+
],
|
| 84 |
+
...,
|
| 85 |
+
"unet": [
|
| 86 |
+
"diffusers",
|
| 87 |
+
"UNet2DConditionModel"
|
| 88 |
+
],
|
| 89 |
+
"vae": [
|
| 90 |
+
"diffusers",
|
| 91 |
+
"AutoencoderKL"
|
| 92 |
+
]
|
| 93 |
+
}
|
| 94 |
+
```
|
| 95 |
+
|
| 96 |
+
이 모델은 약 14억 개의 파라미터로 구성되어 있으므로 GPU에서 파이프라인을 실행할 것을 강력히 권장합니다.
|
| 97 |
+
PyTorch에서와 마찬가지로 제너레이터 객체를 GPU로 이동할 수 있습니다:
|
| 98 |
+
|
| 99 |
+
```python
|
| 100 |
+
>>> pipeline.to("cuda")
|
| 101 |
+
```
|
| 102 |
+
|
| 103 |
+
이제 `파이프라인`에 텍스트 프롬프트를 전달하여 이미지를 생성한 다음 노이즈가 제거된 이미지에 액세스할 수 있습니다. 기본적으로 이미지 출력은 [`PIL.Image`](https://pillow.readthedocs.io/en/stable/reference/Image.html?highlight=image#the-image-class) 객체로 감싸집니다.
|
| 104 |
+
|
| 105 |
+
```python
|
| 106 |
+
>>> image = pipeline("An image of a squirrel in Picasso style").images[0]
|
| 107 |
+
>>> image
|
| 108 |
+
```
|
| 109 |
+
|
| 110 |
+
<div class="flex justify-center">
|
| 111 |
+
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/image_of_squirrel_painting.png"/>
|
| 112 |
+
</div>
|
| 113 |
+
|
| 114 |
+
`save`를 호출하여 이미지를 저장합니다:
|
| 115 |
+
|
| 116 |
+
```python
|
| 117 |
+
>>> image.save("image_of_squirrel_painting.png")
|
| 118 |
+
```
|
| 119 |
+
|
| 120 |
+
### 로컬 파이프라인
|
| 121 |
+
|
| 122 |
+
파이프라인을 로컬에서 사용할 수도 있습니다. 유일한 차이점은 가중치를 먼저 다운로드해야 한다는 점입니다:
|
| 123 |
+
|
| 124 |
+
```bash
|
| 125 |
+
!git lfs install
|
| 126 |
+
!git clone https://huggingface.co/stable-diffusion-v1-5/stable-diffusion-v1-5
|
| 127 |
+
```
|
| 128 |
+
|
| 129 |
+
그런 다음 저장된 가중치를 파이프라인에 로드합니다:
|
| 130 |
+
|
| 131 |
+
```python
|
| 132 |
+
>>> pipeline = DiffusionPipeline.from_pretrained("./stable-diffusion-v1-5")
|
| 133 |
+
```
|
| 134 |
+
|
| 135 |
+
이제 위 섹션에서와 같이 파이프라인을 실행할 수 있습니다.
|
| 136 |
+
|
| 137 |
+
### 스케줄러 교체
|
| 138 |
+
|
| 139 |
+
스케줄러마다 노이즈 제거 속도와 품질이 서로 다릅니다. 자신에게 가장 적합한 스케줄러를 찾는 가장 좋은 방법은 직접 사용해 보는 것입니다! 🧨 Diffusers의 주요 기능 중 하나는 스케줄러 간에 쉽게 전환이 가능하다는 것입니다. 예를 들어, 기본 스케줄러인 [`PNDMScheduler`]를 [`EulerDiscreteScheduler`]로 바꾸려면, [`~diffusers.ConfigMixin.from_config`] 메서드를 사용하여 로드하세요:
|
| 140 |
+
|
| 141 |
+
```py
|
| 142 |
+
>>> from diffusers import EulerDiscreteScheduler
|
| 143 |
+
|
| 144 |
+
>>> pipeline = DiffusionPipeline.from_pretrained("stable-diffusion-v1-5/stable-diffusion-v1-5")
|
| 145 |
+
>>> pipeline.scheduler = EulerDiscreteScheduler.from_config(pipeline.scheduler.config)
|
| 146 |
+
```
|
| 147 |
+
|
| 148 |
+
새 스케줄러로 이미지를 생성해보고 어떤 차이가 있는지 확인해 보세요!
|
| 149 |
+
|
| 150 |
+
다음 섹션에서는 모델과 스케줄러라는 [`DiffusionPipeline`]을 구성하는 컴포넌트를 자세히 살펴보고 이러한 컴포넌트를 사용하여 고양이 이미지를 생성하는 방법을 배워보겠습니다.
|
| 151 |
+
|
| 152 |
+
## 모델
|
| 153 |
+
|
| 154 |
+
대부분의 모델은 노이즈가 있는 샘플을 가져와 각 시간 간격마다 노이즈가 적은 이미지와 입력 이미지 사이의 차이인 *노이즈 잔차*(다른 모델은 이전 샘플을 직접 예측하거나 속도 또는 [`v-prediction`](https://github.com/huggingface/diffusers/blob/5e5ce13e2f89ac45a0066cb3f369462a3cf1d9ef/src/diffusers/schedulers/scheduling_ddim.py#L110)을 예측하는 학습을 합니다)을 예측합니다. 모델을 믹스 앤 매치하여 다른 diffusion 시스템을 만들 수 있습니다.
|
| 155 |
+
|
| 156 |
+
모델은 [`~ModelMixin.from_pretrained`] 메서드로 시작되며, 이 메서드는 모델 가중치를 로컬에 캐시하여 다음에 모델을 로드할 때 더 빠���게 로드할 수 있습니다. 훑어보기에서는 고양이 이미지에 대해 학습된 체크포인트가 있는 기본적인 unconditional 이미지 생성 모델인 [`UNet2DModel`]을 로드합니다:
|
| 157 |
+
|
| 158 |
+
```py
|
| 159 |
+
>>> from diffusers import UNet2DModel
|
| 160 |
+
|
| 161 |
+
>>> repo_id = "google/ddpm-cat-256"
|
| 162 |
+
>>> model = UNet2DModel.from_pretrained(repo_id)
|
| 163 |
+
```
|
| 164 |
+
|
| 165 |
+
모델 매개변수에 액세스하려면 `model.config`를 호출합니다:
|
| 166 |
+
|
| 167 |
+
```py
|
| 168 |
+
>>> model.config
|
| 169 |
+
```
|
| 170 |
+
|
| 171 |
+
모델 구성은 🧊 고정된 🧊 딕셔너리로, 모델이 생성된 후에는 해당 매개 변수들을 변경할 수 없습니다. 이는 의도적인 것으로, 처음에 모델 아키텍처를 정의하는 데 사용된 매개변수는 동일하게 유지하면서 다른 매개변수는 추론 중에 조정할 수 있도록 하기 위한 것입니다.
|
| 172 |
+
|
| 173 |
+
가장 중요한 매개변수들은 다음과 같습니다:
|
| 174 |
+
|
| 175 |
+
* `sample_size`: 입력 샘플의 높이 및 너비 치수입니다.
|
| 176 |
+
* `in_channels`: 입력 샘플의 입력 채널 수입니다.
|
| 177 |
+
* `down_block_types` 및 `up_block_types`: UNet 아키텍처를 생성하는 데 사용되는 다운 및 업샘플링 블록의 유형.
|
| 178 |
+
* `block_out_channels`: 다운샘플링 블록의 출력 채널 수. 업샘플링 블록의 입력 채널 수에 역순으로 사용되기도 합니다.
|
| 179 |
+
* `layers_per_block`: 각 UNet 블록에 존재하는 ResNet 블록의 수입니다.
|
| 180 |
+
|
| 181 |
+
추론에 모델을 사용하려면 랜덤 가우시안 노이즈로 이미지 모양을 만듭니다. 모델이 여러 개의 무작위 노이즈를 수신할 수 있으므로 'batch' 축, 입력 채널 수에 해당하는 'channel' 축, 이미지의 높이와 너비를 나타내는 'sample_size' 축이 있어야 합니다:
|
| 182 |
+
|
| 183 |
+
```py
|
| 184 |
+
>>> import torch
|
| 185 |
+
|
| 186 |
+
>>> torch.manual_seed(0)
|
| 187 |
+
|
| 188 |
+
>>> noisy_sample = torch.randn(1, model.config.in_channels, model.config.sample_size, model.config.sample_size)
|
| 189 |
+
>>> noisy_sample.shape
|
| 190 |
+
torch.Size([1, 3, 256, 256])
|
| 191 |
+
```
|
| 192 |
+
|
| 193 |
+
추론을 위해 모델에 노이즈가 있는 이미지와 `timestep`을 전달합니다. 'timestep'은 입력 이미지의 노이즈 정도를 나타내며, 시작 부분에 더 많은 노이즈가 있고 끝 부분에 더 적은 노이즈가 있습니다. 이를 통해 모델이 diffusion 과정에서 시작 또는 끝에 더 가까운 위치를 결정할 수 있습니다. `sample` 메서드를 사용하여 모델 출력을 얻습니다:
|
| 194 |
+
|
| 195 |
+
```py
|
| 196 |
+
>>> with torch.no_grad():
|
| 197 |
+
... noisy_residual = model(sample=noisy_sample, timestep=2).sample
|
| 198 |
+
```
|
| 199 |
+
|
| 200 |
+
하지만 실제 예를 생성하려면 노이즈 제거 프로세스를 안내할 스케줄러가 필요합니다. 다음 섹션에서는 모델을 스케줄러와 결합하는 방법에 대해 알아봅니다.
|
| 201 |
+
|
| 202 |
+
## 스케줄러
|
| 203 |
+
|
| 204 |
+
스케줄러는 모델 출력이 주어졌을 때 노이즈가 많은 샘플에서 노이즈가 적은 샘플로 전환하는 것을 관리합니다 - 이 경우 'noisy_residual'.
|
| 205 |
+
|
| 206 |
+
<Tip>
|
| 207 |
+
|
| 208 |
+
🧨 Diffusers는 Diffusion 시스템을 구축하기 위한 툴박스입니다. [`DiffusionPipeline`]을 사용하면 미리 만들어진 Diffusion 시스템을 편리하게 시작할 수 있지만, 모델과 스케줄러 구성 요소를 개별적으로 선택하여 사용자 지정 Diffusion 시스템을 구축할 수도 있습니다.
|
| 209 |
+
|
| 210 |
+
</Tip>
|
| 211 |
+
|
| 212 |
+
훑어보기의 경우, [`~diffusers.ConfigMixin.from_config`] 메서드를 사용하여 [`DDPMScheduler`]를 인스턴스화합니다:
|
| 213 |
+
|
| 214 |
+
```py
|
| 215 |
+
>>> from diffusers import DDPMScheduler
|
| 216 |
+
|
| 217 |
+
>>> scheduler = DDPMScheduler.from_config(repo_id)
|
| 218 |
+
>>> scheduler
|
| 219 |
+
DDPMScheduler {
|
| 220 |
+
"_class_name": "DDPMScheduler",
|
| 221 |
+
"_diffusers_version": "0.13.1",
|
| 222 |
+
"beta_end": 0.02,
|
| 223 |
+
"beta_schedule": "linear",
|
| 224 |
+
"beta_start": 0.0001,
|
| 225 |
+
"clip_sample": true,
|
| 226 |
+
"clip_sample_range": 1.0,
|
| 227 |
+
"num_train_timesteps": 1000,
|
| 228 |
+
"prediction_type": "epsilon",
|
| 229 |
+
"trained_betas": null,
|
| 230 |
+
"variance_type": "fixed_small"
|
| 231 |
+
}
|
| 232 |
+
```
|
| 233 |
+
|
| 234 |
+
<Tip>
|
| 235 |
+
|
| 236 |
+
💡 스케줄러가 구성에서 어떻게 인스턴스화되는지 주목하세요. 모델과 달리 스케줄러에는 학습 가능한 가중치가 없으며 매개변수도 없습니다!
|
| 237 |
+
|
| 238 |
+
</Tip>
|
| 239 |
+
|
| 240 |
+
가장 중요한 매개변수는 다음과 같습니다:
|
| 241 |
+
|
| 242 |
+
* `num_train_timesteps`: 노이즈 제거 프로세스의 길이, 즉 랜덤 가우스 노이즈를 데이터 샘플로 처리하는 데 필요한 타임스텝 수입니다.
|
| 243 |
+
* `beta_schedule`: 추론 및 학습에 사용할 노이즈 스케줄 유형입니다.
|
| 244 |
+
* `beta_start` 및 `beta_end`: 노이즈 스케줄의 시작 및 종료 노이즈 값입니다.
|
| 245 |
+
|
| 246 |
+
노이즈가 약간 적은 이미지를 예측하려면 스케줄러의 [`~diffusers.DDPMScheduler.step`] 메서드에 모델 출력, `timestep`, 현재 `sample`을 전달하세요.
|
| 247 |
+
|
| 248 |
+
```py
|
| 249 |
+
>>> less_noisy_sample = scheduler.step(model_output=noisy_residual, timestep=2, sample=noisy_sample).prev_sample
|
| 250 |
+
>>> less_noisy_sample.shape
|
| 251 |
+
```
|
| 252 |
+
|
| 253 |
+
`less_noisy_sample`을 다음 `timestep`으로 넘기면 노이즈가 더 줄어듭니다! 이제 이 모든 것을 한데 모아 전체 노이즈 제거 과정을 시각화해 보겠습니다.
|
| 254 |
+
|
| 255 |
+
먼저 노이즈 제거된 ���미지를 후처리하여 `PIL.Image`로 표시하는 함수를 만듭니다:
|
| 256 |
+
|
| 257 |
+
```py
|
| 258 |
+
>>> import PIL.Image
|
| 259 |
+
>>> import numpy as np
|
| 260 |
+
|
| 261 |
+
|
| 262 |
+
>>> def display_sample(sample, i):
|
| 263 |
+
... image_processed = sample.cpu().permute(0, 2, 3, 1)
|
| 264 |
+
... image_processed = (image_processed + 1.0) * 127.5
|
| 265 |
+
... image_processed = image_processed.numpy().astype(np.uint8)
|
| 266 |
+
|
| 267 |
+
... image_pil = PIL.Image.fromarray(image_processed[0])
|
| 268 |
+
... display(f"Image at step {i}")
|
| 269 |
+
... display(image_pil)
|
| 270 |
+
```
|
| 271 |
+
|
| 272 |
+
노이즈 제거 프로세스의 속도를 높이려면 입력과 모델을 GPU로 옮기세요:
|
| 273 |
+
|
| 274 |
+
```py
|
| 275 |
+
>>> model.to("cuda")
|
| 276 |
+
>>> noisy_sample = noisy_sample.to("cuda")
|
| 277 |
+
```
|
| 278 |
+
|
| 279 |
+
이제 노이즈가 적은 샘플의 잔차를 예측하고 스케줄러로 노이즈가 적은 샘플을 계산하는 노이즈 제거 루프를 생성합니다:
|
| 280 |
+
|
| 281 |
+
```py
|
| 282 |
+
>>> import tqdm
|
| 283 |
+
|
| 284 |
+
>>> sample = noisy_sample
|
| 285 |
+
|
| 286 |
+
>>> for i, t in enumerate(tqdm.tqdm(scheduler.timesteps)):
|
| 287 |
+
... # 1. predict noise residual
|
| 288 |
+
... with torch.no_grad():
|
| 289 |
+
... residual = model(sample, t).sample
|
| 290 |
+
|
| 291 |
+
... # 2. compute less noisy image and set x_t -> x_t-1
|
| 292 |
+
... sample = scheduler.step(residual, t, sample).prev_sample
|
| 293 |
+
|
| 294 |
+
... # 3. optionally look at image
|
| 295 |
+
... if (i + 1) % 50 == 0:
|
| 296 |
+
... display_sample(sample, i + 1)
|
| 297 |
+
```
|
| 298 |
+
|
| 299 |
+
가만히 앉아서 고양이가 소음으로만 생성되는 것을 지켜보세요!😻
|
| 300 |
+
|
| 301 |
+
<div class="flex justify-center">
|
| 302 |
+
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/diffusion-quicktour.png"/>
|
| 303 |
+
</div>
|
| 304 |
+
|
| 305 |
+
## 다음 단계
|
| 306 |
+
|
| 307 |
+
이번 훑어보기에서 🧨 Diffusers로 멋진 이미지를 만들어 보셨기를 바랍니다! 다음 단계로 넘어가세요:
|
| 308 |
+
|
| 309 |
+
* [training](./tutorials/basic_training) 튜토리얼에서 모델을 학습하거나 파인튜닝하여 나만의 이미지를 생성할 수 있습니다.
|
| 310 |
+
* 다양한 사용 사례는 공식 및 커뮤니티 [학습 또는 파인튜닝 스크립트](https://github.com/huggingface/diffusers/tree/main/examples#-diffusers-examples) 예시를 참조하세요.
|
| 311 |
+
* 스케줄러 로드, 액세스, 변경 및 비교에 대한 자세한 내용은 [다른 스케줄러 사용](./using-diffusers/schedulers) 가이드에서 확인하세요.
|
| 312 |
+
* [Stable Diffusion](./stable_diffusion) 가이드에서 프롬프트 엔지니어링, 속도 및 메모리 최적화, 고품질 이미지 생성을 위한 팁과 요령을 살펴보세요.
|
| 313 |
+
* [GPU에서 파이토치 최적화](./optimization/fp16) 가이드와 [애플 실리콘(M1/M2)에서의 Stable Diffusion](./optimization/mps) 및 [ONNX 런타임](./optimization/onnx) 실행에 대한 추론 가이드를 통해 🧨 Diffuser 속도를 높이는 방법을 더 자세히 알아보세요.
|
tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/stable_diffusion.md
ADDED
|
@@ -0,0 +1,279 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2024 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# 효과적이고 효율적인 Diffusion
|
| 14 |
+
|
| 15 |
+
[[open-in-colab]]
|
| 16 |
+
|
| 17 |
+
특정 스타일로 이미지를 생성하거나 원하는 내용을 포함하도록[`DiffusionPipeline`]을 설정하는 것은 까다로울 수 있습니다. 종종 만족스러운 이미지를 얻기까지 [`DiffusionPipeline`]을 여러 번 실행해야 하는 경우가 많습니다. 그러나 무에서 유를 창조하는 것은 특히 추론을 반복해서 실행하는 경우 계산 집약적인 프로세스입니다.
|
| 18 |
+
|
| 19 |
+
그렇기 때문에 파이프라인에서 *계산*(속도) 및 *메모리*(GPU RAM) 효율성을 극대화하여 추론 주기 사이의 시간을 단축하여 더 빠르게 반복할 수 있도록 하는 것이 중요합니다.
|
| 20 |
+
|
| 21 |
+
이 튜토리얼에서는 [`DiffusionPipeline`]을 사용하여 더 빠르고 효과적으로 생성하는 방법을 안내합니다.
|
| 22 |
+
|
| 23 |
+
[`stable-diffusion-v1-5/stable-diffusion-v1-5`](https://huggingface.co/stable-diffusion-v1-5/stable-diffusion-v1-5) 모델을 불러와서 시작합니다:
|
| 24 |
+
|
| 25 |
+
```python
|
| 26 |
+
from diffusers import DiffusionPipeline
|
| 27 |
+
|
| 28 |
+
model_id = "stable-diffusion-v1-5/stable-diffusion-v1-5"
|
| 29 |
+
pipeline = DiffusionPipeline.from_pretrained(model_id)
|
| 30 |
+
```
|
| 31 |
+
|
| 32 |
+
예제 프롬프트는 "portrait of an old warrior chief" 이지만, 자유롭게 자신만의 프롬프트를 사용해도 됩니다:
|
| 33 |
+
|
| 34 |
+
```python
|
| 35 |
+
prompt = "portrait photo of a old warrior chief"
|
| 36 |
+
```
|
| 37 |
+
|
| 38 |
+
## 속도
|
| 39 |
+
|
| 40 |
+
<Tip>
|
| 41 |
+
|
| 42 |
+
💡 GPU에 액세스할 수 없는 경우 다음과 같은 GPU 제공업체에서 무료로 사용할 수 있습니다!. [Colab](https://colab.research.google.com/)
|
| 43 |
+
|
| 44 |
+
</Tip>
|
| 45 |
+
|
| 46 |
+
추론 속도를 높이는 가장 간단한 방법 중 하나는 Pytorch 모듈을 사용할 때와 같은 방식으로 GPU에 파이프라인을 배치하는 것입니다:
|
| 47 |
+
|
| 48 |
+
```python
|
| 49 |
+
pipeline = pipeline.to("cuda")
|
| 50 |
+
```
|
| 51 |
+
|
| 52 |
+
동일한 이미지를 사용하고 개선할 수 있는지 확인하려면 [`Generator`](https://pytorch.org/docs/stable/generated/torch.Generator.html)를 사용하고 [재현성](./using-diffusers/reusing_seeds)에 대한 시드를 설정하세요:
|
| 53 |
+
|
| 54 |
+
```python
|
| 55 |
+
import torch
|
| 56 |
+
|
| 57 |
+
generator = torch.Generator("cuda").manual_seed(0)
|
| 58 |
+
```
|
| 59 |
+
|
| 60 |
+
이제 이미지를 생성할 수 있습니다:
|
| 61 |
+
|
| 62 |
+
```python
|
| 63 |
+
image = pipeline(prompt, generator=generator).images[0]
|
| 64 |
+
image
|
| 65 |
+
```
|
| 66 |
+
|
| 67 |
+
<div class="flex justify-center">
|
| 68 |
+
<img src="https://huggingface.co/datasets/diffusers/docs-images/resolve/main/stable_diffusion_101/sd_101_1.png">
|
| 69 |
+
</div>
|
| 70 |
+
|
| 71 |
+
이 프로세스는 T4 GPU에서 약 30초가 소요되었습니다(할당된 GPU가 T4보다 나은 경우 더 빠를 수 있음). 기본적으로 [`DiffusionPipeline`]은 50개의 추론 단계에 대해 전체 `float32` 정밀도로 추론을 실행합니다. `float16`과 같은 더 낮은 정밀도로 전환하거나 추론 단계를 더 적게 실행하여 속도를 높일 수 있습니다.
|
| 72 |
+
|
| 73 |
+
`float16`으로 모델을 로드하고 이미지를 생성해 보겠습니다:
|
| 74 |
+
|
| 75 |
+
|
| 76 |
+
```python
|
| 77 |
+
import torch
|
| 78 |
+
|
| 79 |
+
pipeline = DiffusionPipeline.from_pretrained(model_id, torch_dtype=torch.float16)
|
| 80 |
+
pipeline = pipeline.to("cuda")
|
| 81 |
+
generator = torch.Generator("cuda").manual_seed(0)
|
| 82 |
+
image = pipeline(prompt, generator=generator).images[0]
|
| 83 |
+
image
|
| 84 |
+
```
|
| 85 |
+
|
| 86 |
+
<div class="flex justify-center">
|
| 87 |
+
<img src="https://huggingface.co/datasets/diffusers/docs-images/resolve/main/stable_diffusion_101/sd_101_2.png">
|
| 88 |
+
</div>
|
| 89 |
+
|
| 90 |
+
이번에는 이미지를 생성하는 데 약 11초밖에 걸리지 않아 이전보다 3배 가까이 빨라졌습니다!
|
| 91 |
+
|
| 92 |
+
<Tip>
|
| 93 |
+
|
| 94 |
+
💡 파이프라인은 항상 `float16`에서 실행할 것을 강력히 권장하며, 지금까지 출력 품질이 저하되는 경우는 거의 없었습니다.
|
| 95 |
+
|
| 96 |
+
</Tip>
|
| 97 |
+
|
| 98 |
+
또 다른 옵션은 추론 단계의 수를 줄이는 것입니다. 보다 효율적인 스케줄러를 선택하면 출력 품질 저하 없이 단계 수를 줄이는 데 도움이 될 수 있습니다. 현재 모델과 호환되는 스케줄러는 `compatibles` 메서드를 호출하여 [`DiffusionPipeline`]에서 찾을 수 있습니다:
|
| 99 |
+
|
| 100 |
+
```python
|
| 101 |
+
pipeline.scheduler.compatibles
|
| 102 |
+
[
|
| 103 |
+
diffusers.schedulers.scheduling_lms_discrete.LMSDiscreteScheduler,
|
| 104 |
+
diffusers.schedulers.scheduling_unipc_multistep.UniPCMultistepScheduler,
|
| 105 |
+
diffusers.schedulers.scheduling_k_dpm_2_discrete.KDPM2DiscreteScheduler,
|
| 106 |
+
diffusers.schedulers.scheduling_deis_multistep.DEISMultistepScheduler,
|
| 107 |
+
diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler,
|
| 108 |
+
diffusers.schedulers.scheduling_dpmsolver_multistep.DPMSolverMultistepScheduler,
|
| 109 |
+
diffusers.schedulers.scheduling_ddpm.DDPMScheduler,
|
| 110 |
+
diffusers.schedulers.scheduling_dpmsolver_singlestep.DPMSolverSinglestepScheduler,
|
| 111 |
+
diffusers.schedulers.scheduling_k_dpm_2_ancestral_discrete.KDPM2AncestralDiscreteScheduler,
|
| 112 |
+
diffusers.schedulers.scheduling_heun_discrete.HeunDiscreteScheduler,
|
| 113 |
+
diffusers.schedulers.scheduling_pndm.PNDMScheduler,
|
| 114 |
+
diffusers.schedulers.scheduling_euler_ancestral_discrete.EulerAncestralDiscreteScheduler,
|
| 115 |
+
diffusers.schedulers.scheduling_ddim.DDIMScheduler,
|
| 116 |
+
]
|
| 117 |
+
```
|
| 118 |
+
|
| 119 |
+
Stable Diffusion 모델은 일반적으로 약 50개의 추론 단계가 필요한 [`PNDMScheduler`]를 기본으로 사용하지만, [`DPMSolverMultistepScheduler`]와 같이 성능이 더 뛰어난 스케줄러는 약 20개 또는 25개의 추론 단계만 필요로 합니다. 새 스케줄러를 로드하려면 [`ConfigMixin.from_config`] 메서드를 사용합니다:
|
| 120 |
+
|
| 121 |
+
```python
|
| 122 |
+
from diffusers import DPMSolverMultistepScheduler
|
| 123 |
+
|
| 124 |
+
pipeline.scheduler = DPMSolverMultistepScheduler.from_config(pipeline.scheduler.config)
|
| 125 |
+
```
|
| 126 |
+
|
| 127 |
+
`num_inference_steps`를 20으로 설정합니다:
|
| 128 |
+
|
| 129 |
+
```python
|
| 130 |
+
generator = torch.Generator("cuda").manual_seed(0)
|
| 131 |
+
image = pipeline(prompt, generator=generator, num_inference_steps=20).images[0]
|
| 132 |
+
image
|
| 133 |
+
```
|
| 134 |
+
|
| 135 |
+
<div class="flex justify-center">
|
| 136 |
+
<img src="https://huggingface.co/datasets/diffusers/docs-images/resolve/main/stable_diffusion_101/sd_101_3.png">
|
| 137 |
+
</div>
|
| 138 |
+
|
| 139 |
+
추론시간을 4초로 단축할 수 있었습니다! ⚡️
|
| 140 |
+
|
| 141 |
+
## 메모리
|
| 142 |
+
|
| 143 |
+
파이프라인 성능 향상의 또 다른 핵심은 메모리 사용량을 줄이는 것인데, 초당 생성되는 이미지 수를 최대화하려고 하는 경우가 많기 때문에 간접적으로 더 빠른 속도를 의미합니다. 한 번에 생성할 수 있는 이미지 수를 확인하는 가장 쉬운 방법은 `OutOfMemoryError`(OOM)이 발생할 때까지 다양한 배치 크기를 시도해 보는 것입니다.
|
| 144 |
+
|
| 145 |
+
프롬프트 목록과 `Generators`에서 이미지 배치를 생성하는 함수를 만듭니다. 좋은 결과를 생성하는 경우 재사용할 수 있도록 각 `Generator`에 시드를 할당해야 합니다.
|
| 146 |
+
|
| 147 |
+
```python
|
| 148 |
+
def get_inputs(batch_size=1):
|
| 149 |
+
generator = [torch.Generator("cuda").manual_seed(i) for i in range(batch_size)]
|
| 150 |
+
prompts = batch_size * [prompt]
|
| 151 |
+
num_inference_steps = 20
|
| 152 |
+
|
| 153 |
+
return {"prompt": prompts, "generator": generator, "num_inference_steps": num_inference_steps}
|
| 154 |
+
```
|
| 155 |
+
|
| 156 |
+
또한 각 이미지 배치를 보여주는 기능이 필요합니다:
|
| 157 |
+
|
| 158 |
+
```python
|
| 159 |
+
from PIL import Image
|
| 160 |
+
|
| 161 |
+
|
| 162 |
+
def image_grid(imgs, rows=2, cols=2):
|
| 163 |
+
w, h = imgs[0].size
|
| 164 |
+
grid = Image.new("RGB", size=(cols * w, rows * h))
|
| 165 |
+
|
| 166 |
+
for i, img in enumerate(imgs):
|
| 167 |
+
grid.paste(img, box=(i % cols * w, i // cols * h))
|
| 168 |
+
return grid
|
| 169 |
+
```
|
| 170 |
+
|
| 171 |
+
`batch_size=4`부터 시작해 얼마나 많은 메모리를 소비했는지 확인합니다:
|
| 172 |
+
|
| 173 |
+
```python
|
| 174 |
+
images = pipeline(**get_inputs(batch_size=4)).images
|
| 175 |
+
image_grid(images)
|
| 176 |
+
```
|
| 177 |
+
|
| 178 |
+
RAM이 더 많은 GPU가 아니라면 위의 코드에서 `OOM` 오류가 반환되었을 것입니다! 대부분의 메모리는 cross-attention 레이어가 차지합니다. 이 작업을 배치로 실행하는 대신 순차적으로 실행하면 상당한 양의 메모리를 절약할 수 있습니다. 파이프라인을 구성하여 [`~DiffusionPipeline.enable_attention_slicing`] 함수를 사용하기만 하면 됩니다:
|
| 179 |
+
|
| 180 |
+
|
| 181 |
+
```python
|
| 182 |
+
pipeline.enable_attention_slicing()
|
| 183 |
+
```
|
| 184 |
+
|
| 185 |
+
이제 `batch_size`를 8로 늘려보세요!
|
| 186 |
+
|
| 187 |
+
```python
|
| 188 |
+
images = pipeline(**get_inputs(batch_size=8)).images
|
| 189 |
+
image_grid(images, rows=2, cols=4)
|
| 190 |
+
```
|
| 191 |
+
|
| 192 |
+
<div class="flex justify-center">
|
| 193 |
+
<img src="https://huggingface.co/datasets/diffusers/docs-images/resolve/main/stable_diffusion_101/sd_101_5.png">
|
| 194 |
+
</div>
|
| 195 |
+
|
| 196 |
+
이전에는 4개의 이미지를 배치로 생성할 수도 없었지만, 이제는 이미지당 약 3.5초 만에 8개의 이미지를 배치로 생성할 수 있습니다! 이는 아마도 품질 저하 없이 T4 GPU에서 가장 빠른 속도일 것입니다.
|
| 197 |
+
|
| 198 |
+
## 품질
|
| 199 |
+
|
| 200 |
+
지난 두 섹션에서는 `fp16`을 사용하여 파이프라인의 속도를 최적화하고, 더 성능이 좋은 스케줄러를 사용하여 추론 단계의 수를 줄이고, attention slicing을 활성화하여 메모리 소비를 줄이는 방법을 배웠습니다. 이제 생성된 이미지의 품질을 개선하는 방법에 대해 집중적으로 알아보겠습니다.
|
| 201 |
+
|
| 202 |
+
|
| 203 |
+
### 더 나은 체크포인트
|
| 204 |
+
|
| 205 |
+
가장 확실한 단계는 더 나은 체크포인트를 사용하는 것입니다. Stable Diffusion 모델은 좋은 출발점이며, 공식 출시 이후 몇 가지 개선된 버전도 출시되었습니다. 하지만 최신 버전을 사용한다고 해서 자동으로 더 나은 결과를 얻을 수 있는 것은 아닙니다. 여전히 다양한 체크포인트를 직접 실험해보고, [negative prompts](https://minimaxir.com/2022/11/stable-diffusion-negative-prompt/) 사용 등 약간의 조사를 통해 최상의 결과를 얻어야 합니다.
|
| 206 |
+
|
| 207 |
+
이 분야가 성장함에 따라 특정 스타일을 연출할 수 있도록 세밀하게 조정된 고품질 체크포인트가 점점 더 많아지고 있습니다. [Hub](https://huggingface.co/models?library=diffusers&sort=downloads)와 [Diffusers Gallery](https://huggingface.co/spaces/huggingface-projects/diffusers-gallery)를 둘러보고 관심 있는 것을 찾아보세요!
|
| 208 |
+
|
| 209 |
+
|
| 210 |
+
### 더 나은 파이프라인 구성 요소
|
| 211 |
+
|
| 212 |
+
현재 파이프라인 구성 요소를 최신 버전으로 교체해 볼 수도 있습니다. Stability AI의 최신 [autodecoder](https://huggingface.co/stabilityai/stable-diffusion-2-1/tree/main/vae)를 파이프라인에 로드하고 몇 가지 이미지를 생성해 보겠습니다:
|
| 213 |
+
|
| 214 |
+
|
| 215 |
+
```python
|
| 216 |
+
from diffusers import AutoencoderKL
|
| 217 |
+
|
| 218 |
+
vae = AutoencoderKL.from_pretrained("stabilityai/sd-vae-ft-mse", torch_dtype=torch.float16).to("cuda")
|
| 219 |
+
pipeline.vae = vae
|
| 220 |
+
images = pipeline(**get_inputs(batch_size=8)).images
|
| 221 |
+
image_grid(images, rows=2, cols=4)
|
| 222 |
+
```
|
| 223 |
+
|
| 224 |
+
<div class="flex justify-center">
|
| 225 |
+
<img src="https://huggingface.co/datasets/diffusers/docs-images/resolve/main/stable_diffusion_101/sd_101_6.png">
|
| 226 |
+
</div>
|
| 227 |
+
|
| 228 |
+
### 더 나은 프롬프트 엔지니어링
|
| 229 |
+
|
| 230 |
+
이미지를 생성하는 데 사용하는 텍스트 프롬프트는 *prompt engineering*이라고 할 정도로 매우 중요합니다. 프롬프트 엔지니어링 시 고려해야 할 몇 가지 사항은 다음과 같습니다:
|
| 231 |
+
|
| 232 |
+
- 생성하려는 이미지 또는 유사한 이미지가 인터넷에 어떻게 저장되어 있는가?
|
| 233 |
+
- 내가 원하는 스타일로 모델을 유도하기 위해 어떤 추가 세부 정보를 제공할 수 있는가?
|
| 234 |
+
|
| 235 |
+
이를 염두에 두고 색상과 더 높은 품질의 디테일을 포함하도록 프롬프트를 개선해 봅시다:
|
| 236 |
+
|
| 237 |
+
|
| 238 |
+
```python
|
| 239 |
+
prompt += ", tribal panther make up, blue on red, side profile, looking away, serious eyes"
|
| 240 |
+
prompt += " 50mm portrait photography, hard rim lighting photography--beta --ar 2:3 --beta --upbeta"
|
| 241 |
+
```
|
| 242 |
+
|
| 243 |
+
새로운 프롬프트로 이미지 배치를 생성합니다:
|
| 244 |
+
|
| 245 |
+
```python
|
| 246 |
+
images = pipeline(**get_inputs(batch_size=8)).images
|
| 247 |
+
image_grid(images, rows=2, cols=4)
|
| 248 |
+
```
|
| 249 |
+
|
| 250 |
+
<div class="flex justify-center">
|
| 251 |
+
<img src="https://huggingface.co/datasets/diffusers/docs-images/resolve/main/stable_diffusion_101/sd_101_7.png">
|
| 252 |
+
</div>
|
| 253 |
+
|
| 254 |
+
꽤 인상적입니다! `1`의 시드를 가진 `Generator`에 해당하는 두 번째 이미지에 피사체의 나이에 대한 텍스트를 추가하여 조금 더 조정해 보겠습니다:
|
| 255 |
+
|
| 256 |
+
```python
|
| 257 |
+
prompts = [
|
| 258 |
+
"portrait photo of the oldest warrior chief, tribal panther make up, blue on red, side profile, looking away, serious eyes 50mm portrait photography, hard rim lighting photography--beta --ar 2:3 --beta --upbeta",
|
| 259 |
+
"portrait photo of a old warrior chief, tribal panther make up, blue on red, side profile, looking away, serious eyes 50mm portrait photography, hard rim lighting photography--beta --ar 2:3 --beta --upbeta",
|
| 260 |
+
"portrait photo of a warrior chief, tribal panther make up, blue on red, side profile, looking away, serious eyes 50mm portrait photography, hard rim lighting photography--beta --ar 2:3 --beta --upbeta",
|
| 261 |
+
"portrait photo of a young warrior chief, tribal panther make up, blue on red, side profile, looking away, serious eyes 50mm portrait photography, hard rim lighting photography--beta --ar 2:3 --beta --upbeta",
|
| 262 |
+
]
|
| 263 |
+
|
| 264 |
+
generator = [torch.Generator("cuda").manual_seed(1) for _ in range(len(prompts))]
|
| 265 |
+
images = pipeline(prompt=prompts, generator=generator, num_inference_steps=25).images
|
| 266 |
+
image_grid(images)
|
| 267 |
+
```
|
| 268 |
+
|
| 269 |
+
<div class="flex justify-center">
|
| 270 |
+
<img src="https://huggingface.co/datasets/diffusers/docs-images/resolve/main/stable_diffusion_101/sd_101_8.png">
|
| 271 |
+
</div>
|
| 272 |
+
|
| 273 |
+
## 다음 단계
|
| 274 |
+
|
| 275 |
+
이 튜토리얼에서는 계산 및 메모리 효율을 높이고 생성된 출력의 품질을 개선하기 위해 [`DiffusionPipeline`]을 최적화하는 방법을 배웠습니다. 파이프라인을 더 빠르게 만드는 데 관심이 있다면 다음 리소스를 살펴보세요:
|
| 276 |
+
|
| 277 |
+
- [PyTorch 2.0](./optimization/torch2.0) 및 [`torch.compile`](https://pytorch.org/docs/stable/generated/torch.compile.html)이 어떻게 추론 속도를 5~300% 향상시킬 수 있는지 알아보세요. A100 GPU에서는 추론 속도가 최대 50%까지 빨라질 수 있습니다!
|
| 278 |
+
- PyTorch 2를 사용할 수 없는 경우, [xFormers](./optimization/xformers)를 설치하는 것이 좋습니다. 메모리 효율적인 어텐션 메커니즘은 PyTorch 1.13.1과 함께 사용하면 속도가 빨라지고 메모리 소비가 줄어듭니다.
|
| 279 |
+
- 모델 오프로딩과 같은 다른 최적화 기법은 [이 가이드](./optimization/fp16)에서 다루고 있습니다.
|
tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/training/adapt_a_model.md
ADDED
|
@@ -0,0 +1,54 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2024 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# 새로운 작업에 대한 모델을 적용하기
|
| 14 |
+
|
| 15 |
+
많은 diffusion 시스템은 같은 구성 요소들을 공유하므로 한 작업에 대해 사전학습된 모델을 완전히 다른 작업에 적용할 수 있습니다.
|
| 16 |
+
|
| 17 |
+
이 인페인팅을 위한 가이드는 사전학습된 [`UNet2DConditionModel`]의 아키텍처를 초기화하고 수정하여 사전학습된 text-to-image 모델을 어떻게 인페인팅에 적용하는지를 알려줄 것입니다.
|
| 18 |
+
|
| 19 |
+
## UNet2DConditionModel 파라미터 구성
|
| 20 |
+
|
| 21 |
+
[`UNet2DConditionModel`]은 [input sample](https://huggingface.co/docs/diffusers/v0.16.0/en/api/models#diffusers.UNet2DConditionModel.in_channels)에서 4개의 채널을 기본적으로 허용합니다. 예를 들어, [`stable-diffusion-v1-5/stable-diffusion-v1-5`](https://huggingface.co/stable-diffusion-v1-5/stable-diffusion-v1-5)와 같은 사전학습된 text-to-image 모델을 불러오고 `in_channels`의 수를 확인합니다:
|
| 22 |
+
|
| 23 |
+
```py
|
| 24 |
+
from diffusers import StableDiffusionPipeline
|
| 25 |
+
|
| 26 |
+
pipeline = StableDiffusionPipeline.from_pretrained("stable-diffusion-v1-5/stable-diffusion-v1-5")
|
| 27 |
+
pipeline.unet.config["in_channels"]
|
| 28 |
+
4
|
| 29 |
+
```
|
| 30 |
+
|
| 31 |
+
인페인팅은 입력 샘플에 9개의 채널이 필요합니다. [`runwayml/stable-diffusion-inpainting`](https://huggingface.co/runwayml/stable-diffusion-inpainting)와 같은 사전학습된 인페인팅 모델에서 이 값을 확인할 수 있습니다:
|
| 32 |
+
|
| 33 |
+
```py
|
| 34 |
+
from diffusers import StableDiffusionPipeline
|
| 35 |
+
|
| 36 |
+
pipeline = StableDiffusionPipeline.from_pretrained("runwayml/stable-diffusion-inpainting")
|
| 37 |
+
pipeline.unet.config["in_channels"]
|
| 38 |
+
9
|
| 39 |
+
```
|
| 40 |
+
|
| 41 |
+
인페인팅에 대한 text-to-image 모델을 적용하기 위해, `in_channels` 수를 4에서 9로 수정해야 할 것입니다.
|
| 42 |
+
|
| 43 |
+
사전학습된 text-to-image 모델의 가중치와 [`UNet2DConditionModel`]을 초기화하고 `in_channels`를 9로 수정해 주세요. `in_channels`의 수를 수정하면 크기가 달라지기 때문에 크기가 안 맞는 오류를 피하기 위해 `ignore_mismatched_sizes=True` 및 `low_cpu_mem_usage=False`를 설정해야 합니다.
|
| 44 |
+
|
| 45 |
+
```py
|
| 46 |
+
from diffusers import UNet2DConditionModel
|
| 47 |
+
|
| 48 |
+
model_id = "stable-diffusion-v1-5/stable-diffusion-v1-5"
|
| 49 |
+
unet = UNet2DConditionModel.from_pretrained(
|
| 50 |
+
model_id, subfolder="unet", in_channels=9, low_cpu_mem_usage=False, ignore_mismatched_sizes=True
|
| 51 |
+
)
|
| 52 |
+
```
|
| 53 |
+
|
| 54 |
+
Text-to-image 모델로부터 다른 구성 요소의 사전학습된 가중치는 체크포인트로부터 초기화되지만 `unet`의 입력 채널 가중치 (`conv_in.weight`)는 랜덤하게 초기화됩니다. 그렇지 않으면 모델이 노이즈를 리턴하기 때문에 인페인팅의 모델을 파인튜닝 할 때 중요합니다.
|
tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/training/controlnet.md
ADDED
|
@@ -0,0 +1,325 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2024 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# ControlNet
|
| 14 |
+
|
| 15 |
+
[Adding Conditional Control to Text-to-Image Diffusion Models](https://huggingface.co/papers/2302.05543) (ControlNet)은 Lvmin Zhang과 Maneesh Agrawala에 의해 쓰여졌습니다.
|
| 16 |
+
|
| 17 |
+
이 예시는 [원본 ControlNet 리포지토리에서 예시 학습하기](https://github.com/lllyasviel/ControlNet/blob/main/docs/train.md)에 기반합니다. ControlNet은 원들을 채우기 위해 [small synthetic dataset](https://huggingface.co/datasets/fusing/fill50k)을 사용해서 학습됩니다.
|
| 18 |
+
|
| 19 |
+
## 의존성 설치하기
|
| 20 |
+
|
| 21 |
+
아래의 스크립트를 실행하기 전에, 라이브러리의 학습 의존성을 설치해야 합니다.
|
| 22 |
+
|
| 23 |
+
<Tip warning={true}>
|
| 24 |
+
|
| 25 |
+
가장 최신 버전의 예시 스크립트를 성공적으로 실행하기 위해서는, 소스에서 설치하고 최신 버전의 설치를 유지하는 것을 강력하게 추천합니다. 우리는 예시 스크립트들을 자주 업데이트하고 예시에 맞춘 특정한 요구사항을 설치합니다.
|
| 26 |
+
|
| 27 |
+
</Tip>
|
| 28 |
+
|
| 29 |
+
위 사항을 만족시키기 위해서, 새로운 가상환경에서 다음 일련의 스텝을 실행하세요:
|
| 30 |
+
|
| 31 |
+
```bash
|
| 32 |
+
git clone https://github.com/huggingface/diffusers
|
| 33 |
+
cd diffusers
|
| 34 |
+
pip install -e .
|
| 35 |
+
```
|
| 36 |
+
|
| 37 |
+
그 다음에는 [예시 폴더](https://github.com/huggingface/diffusers/tree/main/examples/controlnet)으로 이동합니다.
|
| 38 |
+
|
| 39 |
+
```bash
|
| 40 |
+
cd examples/controlnet
|
| 41 |
+
```
|
| 42 |
+
|
| 43 |
+
이제 실행하세요:
|
| 44 |
+
|
| 45 |
+
```bash
|
| 46 |
+
pip install -r requirements.txt
|
| 47 |
+
```
|
| 48 |
+
|
| 49 |
+
[🤗Accelerate](https://github.com/huggingface/accelerate/) 환경을 초기화 합니다:
|
| 50 |
+
|
| 51 |
+
```bash
|
| 52 |
+
accelerate config
|
| 53 |
+
```
|
| 54 |
+
|
| 55 |
+
혹은 여러분의 환경이 무엇인지 몰라도 기본적인 🤗Accelerate 구성으로 초기화할 수 있습니다:
|
| 56 |
+
|
| 57 |
+
```bash
|
| 58 |
+
accelerate config default
|
| 59 |
+
```
|
| 60 |
+
|
| 61 |
+
혹은 당신의 환경이 노트북 같은 상호작용하는 쉘을 지원하지 않는다면, 아래의 코드로 초기화 할 수 있습니다:
|
| 62 |
+
|
| 63 |
+
```python
|
| 64 |
+
from accelerate.utils import write_basic_config
|
| 65 |
+
|
| 66 |
+
write_basic_config()
|
| 67 |
+
```
|
| 68 |
+
|
| 69 |
+
자체 데이터셋을 사용하기 위해서는 [학습을 위한 데이터셋 생성하기](create_dataset) 가이드를 확인하세요.
|
| 70 |
+
|
| 71 |
+
## 학습
|
| 72 |
+
|
| 73 |
+
이 학습에 사용될 다음 이미지들을 다운로드하세요:
|
| 74 |
+
|
| 75 |
+
```sh
|
| 76 |
+
wget https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/controlnet_training/conditioning_image_1.png
|
| 77 |
+
|
| 78 |
+
wget https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/controlnet_training/conditioning_image_2.png
|
| 79 |
+
```
|
| 80 |
+
|
| 81 |
+
`MODEL_NAME` 환경 변수 (Hub 모델 리포지토리 아이디 혹은 모델 가중치가 있는 디렉토리로 가는 주소)를 명시하고 [`pretrained_model_name_or_path`](https://huggingface.co/docs/diffusers/en/api/diffusion_pipeline#diffusers.DiffusionPipeline.from_pretrained.pretrained_model_name_or_path) 인자로 환경변수를 보냅니다.
|
| 82 |
+
|
| 83 |
+
학습 스크립트는 당신의 리포지토리에 `diffusion_pytorch_model.bin` 파일을 생성하고 저장합니다.
|
| 84 |
+
|
| 85 |
+
```bash
|
| 86 |
+
export MODEL_DIR="stable-diffusion-v1-5/stable-diffusion-v1-5"
|
| 87 |
+
export OUTPUT_DIR="path to save model"
|
| 88 |
+
|
| 89 |
+
accelerate launch train_controlnet.py \
|
| 90 |
+
--pretrained_model_name_or_path=$MODEL_DIR \
|
| 91 |
+
--output_dir=$OUTPUT_DIR \
|
| 92 |
+
--dataset_name=fusing/fill50k \
|
| 93 |
+
--resolution=512 \
|
| 94 |
+
--learning_rate=1e-5 \
|
| 95 |
+
--validation_image "./conditioning_image_1.png" "./conditioning_image_2.png" \
|
| 96 |
+
--validation_prompt "red circle with blue background" "cyan circle with brown floral background" \
|
| 97 |
+
--train_batch_size=4 \
|
| 98 |
+
--push_to_hub
|
| 99 |
+
```
|
| 100 |
+
|
| 101 |
+
이 기본적인 설정으로는 ~38GB VRAM이 필요합니다.
|
| 102 |
+
|
| 103 |
+
기본적으로 학습 스크립트는 결과를 텐서보드에 기록합니다. 가중치(weight)와 편향(bias)을 사용하기 위해 `--report_to wandb` 를 전달합니다.
|
| 104 |
+
|
| 105 |
+
더 작은 batch(배치) 크기로 gradient accumulation(기울기 누적)을 하면 학습 요구사항을 ~20 GB VRAM으로 줄일 수 있습니다.
|
| 106 |
+
|
| 107 |
+
```bash
|
| 108 |
+
export MODEL_DIR="stable-diffusion-v1-5/stable-diffusion-v1-5"
|
| 109 |
+
export OUTPUT_DIR="path to save model"
|
| 110 |
+
|
| 111 |
+
accelerate launch train_controlnet.py \
|
| 112 |
+
--pretrained_model_name_or_path=$MODEL_DIR \
|
| 113 |
+
--output_dir=$OUTPUT_DIR \
|
| 114 |
+
--dataset_name=fusing/fill50k \
|
| 115 |
+
--resolution=512 \
|
| 116 |
+
--learning_rate=1e-5 \
|
| 117 |
+
--validation_image "./conditioning_image_1.png" "./conditioning_image_2.png" \
|
| 118 |
+
--validation_prompt "red circle with blue background" "cyan circle with brown floral background" \
|
| 119 |
+
--train_batch_size=1 \
|
| 120 |
+
--gradient_accumulation_steps=4 \
|
| 121 |
+
--push_to_hub
|
| 122 |
+
```
|
| 123 |
+
|
| 124 |
+
## 여러개 GPU로 학습하기
|
| 125 |
+
|
| 126 |
+
`accelerate` 은 seamless multi-GPU 학습을 고려합니다. `accelerate`과 함께 분산된 학습을 실행하기 위해 [여기](https://huggingface.co/docs/accelerate/basic_tutorials/launch)
|
| 127 |
+
의 설명을 확인하세요. 아래는 예시 명령어입니다:
|
| 128 |
+
|
| 129 |
+
```bash
|
| 130 |
+
export MODEL_DIR="stable-diffusion-v1-5/stable-diffusion-v1-5"
|
| 131 |
+
export OUTPUT_DIR="path to save model"
|
| 132 |
+
|
| 133 |
+
accelerate launch --mixed_precision="fp16" --multi_gpu train_controlnet.py \
|
| 134 |
+
--pretrained_model_name_or_path=$MODEL_DIR \
|
| 135 |
+
--output_dir=$OUTPUT_DIR \
|
| 136 |
+
--dataset_name=fusing/fill50k \
|
| 137 |
+
--resolution=512 \
|
| 138 |
+
--learning_rate=1e-5 \
|
| 139 |
+
--validation_image "./conditioning_image_1.png" "./conditioning_image_2.png" \
|
| 140 |
+
--validation_prompt "red circle with blue background" "cyan circle with brown floral background" \
|
| 141 |
+
--train_batch_size=4 \
|
| 142 |
+
--mixed_precision="fp16" \
|
| 143 |
+
--tracker_project_name="controlnet-demo" \
|
| 144 |
+
--report_to=wandb \
|
| 145 |
+
--push_to_hub
|
| 146 |
+
```
|
| 147 |
+
|
| 148 |
+
## 예시 결과
|
| 149 |
+
|
| 150 |
+
#### 배치 사이즈 8로 300 스텝 이후:
|
| 151 |
+
|
| 152 |
+
| | |
|
| 153 |
+
|-------------------|:-------------------------:|
|
| 154 |
+
| | 푸른 배경과 빨간 원 |
|
| 155 |
+
 |  |
|
| 156 |
+
| | 갈색 꽃 배경과 청록색 원 |
|
| 157 |
+
 |  |
|
| 158 |
+
|
| 159 |
+
#### 배치 사이즈 8로 6000 스텝 이후:
|
| 160 |
+
|
| 161 |
+
| | |
|
| 162 |
+
|-------------------|:-------------------------:|
|
| 163 |
+
| | 푸른 배경과 빨간 원 |
|
| 164 |
+
 |  |
|
| 165 |
+
| | 갈색 꽃 배경과 청록색 원 |
|
| 166 |
+
 |  |
|
| 167 |
+
|
| 168 |
+
## 16GB GPU에서 학습하기
|
| 169 |
+
|
| 170 |
+
16GB GPU에서 학습하기 위해 다음의 최적화를 진행하세요:
|
| 171 |
+
|
| 172 |
+
- 기울기 체크포인트 저장하기
|
| 173 |
+
- bitsandbyte의 [8-bit optimizer](https://github.com/TimDettmers/bitsandbytes#requirements--installation)가 설치되지 않았다면 링크에 연결된 설명서를 보세요.
|
| 174 |
+
|
| 175 |
+
이제 학습 스크립트를 시작할 수 있습니다:
|
| 176 |
+
|
| 177 |
+
```bash
|
| 178 |
+
export MODEL_DIR="stable-diffusion-v1-5/stable-diffusion-v1-5"
|
| 179 |
+
export OUTPUT_DIR="path to save model"
|
| 180 |
+
|
| 181 |
+
accelerate launch train_controlnet.py \
|
| 182 |
+
--pretrained_model_name_or_path=$MODEL_DIR \
|
| 183 |
+
--output_dir=$OUTPUT_DIR \
|
| 184 |
+
--dataset_name=fusing/fill50k \
|
| 185 |
+
--resolution=512 \
|
| 186 |
+
--learning_rate=1e-5 \
|
| 187 |
+
--validation_image "./conditioning_image_1.png" "./conditioning_image_2.png" \
|
| 188 |
+
--validation_prompt "red circle with blue background" "cyan circle with brown floral background" \
|
| 189 |
+
--train_batch_size=1 \
|
| 190 |
+
--gradient_accumulation_steps=4 \
|
| 191 |
+
--gradient_checkpointing \
|
| 192 |
+
--use_8bit_adam \
|
| 193 |
+
--push_to_hub
|
| 194 |
+
```
|
| 195 |
+
|
| 196 |
+
## 12GB GPU에서 학습하기
|
| 197 |
+
|
| 198 |
+
12GB GPU에서 실행하기 위해 다음의 최적화를 진행하세요:
|
| 199 |
+
|
| 200 |
+
- 기울기 체크포인트 저장하기
|
| 201 |
+
- bitsandbyte의 8-bit [optimizer](https://github.com/TimDettmers/bitsandbytes#requirements--installation)(가 설치되지 않았다면 링크에 연결된 설명서를 보세요)
|
| 202 |
+
- [xFormers](https://huggingface.co/docs/diffusers/training/optimization/xformers)(가 설치되지 않았다면 링크에 연결된 설명서를 보세요)
|
| 203 |
+
- 기울기를 `None`으로 설정
|
| 204 |
+
|
| 205 |
+
```bash
|
| 206 |
+
export MODEL_DIR="stable-diffusion-v1-5/stable-diffusion-v1-5"
|
| 207 |
+
export OUTPUT_DIR="path to save model"
|
| 208 |
+
|
| 209 |
+
accelerate launch train_controlnet.py \
|
| 210 |
+
--pretrained_model_name_or_path=$MODEL_DIR \
|
| 211 |
+
--output_dir=$OUTPUT_DIR \
|
| 212 |
+
--dataset_name=fusing/fill50k \
|
| 213 |
+
--resolution=512 \
|
| 214 |
+
--learning_rate=1e-5 \
|
| 215 |
+
--validation_image "./conditioning_image_1.png" "./conditioning_image_2.png" \
|
| 216 |
+
--validation_prompt "red circle with blue background" "cyan circle with brown floral background" \
|
| 217 |
+
--train_batch_size=1 \
|
| 218 |
+
--gradient_accumulation_steps=4 \
|
| 219 |
+
--gradient_checkpointing \
|
| 220 |
+
--use_8bit_adam \
|
| 221 |
+
--enable_xformers_memory_efficient_attention \
|
| 222 |
+
--set_grads_to_none \
|
| 223 |
+
--push_to_hub
|
| 224 |
+
```
|
| 225 |
+
|
| 226 |
+
`pip install xformers`으로 `xformers`을 확실히 설치하고 `enable_xformers_memory_efficient_attention`을 사용하세요.
|
| 227 |
+
|
| 228 |
+
## 8GB GPU에서 학습하기
|
| 229 |
+
|
| 230 |
+
우리는 ControlNet을 지원하기 위한 DeepSpeed를 철저하게 테스트하지 않았습니다. 환경설정이 메모리를 저장할 때,
|
| 231 |
+
그 환경이 성공적으로 학습했는지를 확정하지 않았습니다. 성공한 학습 실행을 위해 설정을 변경해야 할 가능성이 높습니다.
|
| 232 |
+
|
| 233 |
+
8GB GPU에서 실행하기 위해 다음의 최적화를 진행하세요:
|
| 234 |
+
|
| 235 |
+
- 기울기 체크포인트 저장하기
|
| 236 |
+
- bitsandbyte의 8-bit [optimizer](https://github.com/TimDettmers/bitsandbytes#requirements--installation)(가 설치되지 않았다면 링크에 연결된 설명서를 보세요)
|
| 237 |
+
- [xFormers](https://huggingface.co/docs/diffusers/training/optimization/xformers)(가 설치되지 않았다면 링크에 연결된 설명서를 보세요)
|
| 238 |
+
- 기울기를 `None`으로 설정
|
| 239 |
+
- DeepSpeed stage 2 변수와 optimizer 없에기
|
| 240 |
+
- fp16 혼합 정밀도(precision)
|
| 241 |
+
|
| 242 |
+
[DeepSpeed](https://www.deepspeed.ai/)는 CPU 또는 NVME로 텐서를 VRAM에서 오프로드할 수 있습니다.
|
| 243 |
+
이를 위해서 훨씬 더 많은 RAM(약 25 GB)가 필요합니다.
|
| 244 |
+
|
| 245 |
+
DeepSpeed stage 2를 활성화하기 위해서 `accelerate config`로 환경을 구성해야합니다.
|
| 246 |
+
|
| 247 |
+
구성(configuration) 파일은 이런 모습이어야 합니다:
|
| 248 |
+
|
| 249 |
+
```yaml
|
| 250 |
+
compute_environment: LOCAL_MACHINE
|
| 251 |
+
deepspeed_config:
|
| 252 |
+
gradient_accumulation_steps: 4
|
| 253 |
+
offload_optimizer_device: cpu
|
| 254 |
+
offload_param_device: cpu
|
| 255 |
+
zero3_init_flag: false
|
| 256 |
+
zero_stage: 2
|
| 257 |
+
distributed_type: DEEPSPEED
|
| 258 |
+
```
|
| 259 |
+
|
| 260 |
+
<팁>
|
| 261 |
+
|
| 262 |
+
[문서](https://huggingface.co/docs/accelerate/usage_guides/deepspeed)를 더 많은 DeepSpeed 설정 옵션을 위해 보세요.
|
| 263 |
+
|
| 264 |
+
<팁>
|
| 265 |
+
|
| 266 |
+
기본 Adam optimizer를 DeepSpeed'의 Adam
|
| 267 |
+
`deepspeed.ops.adam.DeepSpeedCPUAdam` 으로 바꾸면 상당한 속도 향상을 이룰수 있지만,
|
| 268 |
+
Pytorch와 같은 버전의 CUDA toolchain이 필요합니다. 8-비트 optimizer는 현재 DeepSpeed와
|
| 269 |
+
호환되지 않는 것 같습니다.
|
| 270 |
+
|
| 271 |
+
```bash
|
| 272 |
+
export MODEL_DIR="stable-diffusion-v1-5/stable-diffusion-v1-5"
|
| 273 |
+
export OUTPUT_DIR="path to save model"
|
| 274 |
+
|
| 275 |
+
accelerate launch train_controlnet.py \
|
| 276 |
+
--pretrained_model_name_or_path=$MODEL_DIR \
|
| 277 |
+
--output_dir=$OUTPUT_DIR \
|
| 278 |
+
--dataset_name=fusing/fill50k \
|
| 279 |
+
--resolution=512 \
|
| 280 |
+
--validation_image "./conditioning_image_1.png" "./conditioning_image_2.png" \
|
| 281 |
+
--validation_prompt "red circle with blue background" "cyan circle with brown floral background" \
|
| 282 |
+
--train_batch_size=1 \
|
| 283 |
+
--gradient_accumulation_steps=4 \
|
| 284 |
+
--gradient_checkpointing \
|
| 285 |
+
--enable_xformers_memory_efficient_attention \
|
| 286 |
+
--set_grads_to_none \
|
| 287 |
+
--mixed_precision fp16 \
|
| 288 |
+
--push_to_hub
|
| 289 |
+
```
|
| 290 |
+
|
| 291 |
+
## 추론
|
| 292 |
+
|
| 293 |
+
학습된 모델은 [`StableDiffusionControlNetPipeline`]과 함께 실행될 수 있습니다.
|
| 294 |
+
`base_model_path`와 `controlnet_path` 에 값을 지정하세요 `--pretrained_model_name_or_path` 와
|
| 295 |
+
`--output_dir` 는 학습 스크립트에 개별적으로 지정됩니다.
|
| 296 |
+
|
| 297 |
+
```py
|
| 298 |
+
from diffusers import StableDiffusionControlNetPipeline, ControlNetModel, UniPCMultistepScheduler
|
| 299 |
+
from diffusers.utils import load_image
|
| 300 |
+
import torch
|
| 301 |
+
|
| 302 |
+
base_model_path = "path to model"
|
| 303 |
+
controlnet_path = "path to controlnet"
|
| 304 |
+
|
| 305 |
+
controlnet = ControlNetModel.from_pretrained(controlnet_path, torch_dtype=torch.float16)
|
| 306 |
+
pipe = StableDiffusionControlNetPipeline.from_pretrained(
|
| 307 |
+
base_model_path, controlnet=controlnet, torch_dtype=torch.float16
|
| 308 |
+
)
|
| 309 |
+
|
| 310 |
+
# 더 빠른 스케줄러와 메모리 최적화로 diffusion 프로세스 속도 올리기
|
| 311 |
+
pipe.scheduler = UniPCMultistepScheduler.from_config(pipe.scheduler.config)
|
| 312 |
+
# xformers가 설치되지 않으면 아래 줄을 삭제하기
|
| 313 |
+
pipe.enable_xformers_memory_efficient_attention()
|
| 314 |
+
|
| 315 |
+
pipe.enable_model_cpu_offload()
|
| 316 |
+
|
| 317 |
+
control_image = load_image("./conditioning_image_1.png")
|
| 318 |
+
prompt = "pale golden rod circle with old lace background"
|
| 319 |
+
|
| 320 |
+
# 이미지 생성하기
|
| 321 |
+
generator = torch.manual_seed(0)
|
| 322 |
+
image = pipe(prompt, num_inference_steps=20, generator=generator, image=control_image).images[0]
|
| 323 |
+
|
| 324 |
+
image.save("./output.png")
|
| 325 |
+
```
|
tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/training/create_dataset.md
ADDED
|
@@ -0,0 +1,98 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# 학습을 위한 데이터셋 만들기
|
| 2 |
+
|
| 3 |
+
[Hub](https://huggingface.co/datasets?task_categories=task_categories:text-to-image&sort=downloads) 에는 모델 교육을 위한 많은 데이터셋이 있지만,
|
| 4 |
+
관심이 있거나 사용하고 싶은 데이터셋을 찾을 수 없는 경우 🤗 [Datasets](https://huggingface.co/docs/datasets) 라이브러리를 사용하여 데이터셋을 만들 수 있습니다.
|
| 5 |
+
데이터셋 구조는 모델을 학습하려는 작업에 따라 달라집니다.
|
| 6 |
+
가장 기본적인 데이터셋 구조는 unconditional 이미지 생성과 같은 작업을 위한 이미지 디렉토리입니다.
|
| 7 |
+
또 다른 데이터셋 구조는 이미지 디렉토리와 text-to-image 생성과 같은 작업에 해당하는 텍스트 캡션이 포함된 텍스트 파일일 수 있습니다.
|
| 8 |
+
|
| 9 |
+
이 가이드에는 파인 튜닝할 데이터셋을 만드는 두 가지 방법을 소개합니다:
|
| 10 |
+
|
| 11 |
+
- 이미지 폴더를 `--train_data_dir` 인수에 제공합니다.
|
| 12 |
+
- 데이터셋을 Hub에 업로드하고 데이터셋 리포지토리 id를 `--dataset_name` 인수에 전달합니다.
|
| 13 |
+
|
| 14 |
+
<Tip>
|
| 15 |
+
|
| 16 |
+
💡 학습에 사용할 이미지 데이터셋을 만드는 방법에 대한 자세한 내용은 [이미지 데이터셋 만들기](https://huggingface.co/docs/datasets/image_dataset) 가이드를 참고하세요.
|
| 17 |
+
|
| 18 |
+
</Tip>
|
| 19 |
+
|
| 20 |
+
## 폴더 형태로 데이터셋 구축하기
|
| 21 |
+
|
| 22 |
+
Unconditional 생성을 위해 이미지 폴더로 자신의 데이터셋을 구축할 수 있습니다.
|
| 23 |
+
학습 스크립트는 🤗 Datasets의 [ImageFolder](https://huggingface.co/docs/datasets/en/image_dataset#imagefolder) 빌더를 사용하여
|
| 24 |
+
자동으로 폴더에서 데이터셋을 구축합니다. 디렉토리 구조는 다음과 같아야 합니다 :
|
| 25 |
+
|
| 26 |
+
```bash
|
| 27 |
+
data_dir/xxx.png
|
| 28 |
+
data_dir/xxy.png
|
| 29 |
+
data_dir/[...]/xxz.png
|
| 30 |
+
```
|
| 31 |
+
|
| 32 |
+
데이터셋 디렉터리의 경로를 `--train_data_dir` 인수로 전달한 다음 학습을 시작할 수 있습니다:
|
| 33 |
+
|
| 34 |
+
```bash
|
| 35 |
+
accelerate launch train_unconditional.py \
|
| 36 |
+
# argument로 폴더 지정하기 \
|
| 37 |
+
--train_data_dir <path-to-train-directory> \
|
| 38 |
+
<other-arguments>
|
| 39 |
+
```
|
| 40 |
+
|
| 41 |
+
## Hub에 데이터 올리기
|
| 42 |
+
|
| 43 |
+
<Tip>
|
| 44 |
+
|
| 45 |
+
💡 데이터셋을 만들고 Hub에 업로드하는 것에 대한 자세한 내용은 [🤗 Datasets을 사용한 이미지 검색](https://huggingface.co/blog/image-search-datasets) 게시물을 참고하세요.
|
| 46 |
+
|
| 47 |
+
</Tip>
|
| 48 |
+
|
| 49 |
+
PIL 인코딩된 이미지가 포함된 `이미지` 열을 생성하는 [이미지 폴더](https://huggingface.co/docs/datasets/image_load#imagefolder) 기능을 사용하여 데이터셋 생성을 시작합니다.
|
| 50 |
+
|
| 51 |
+
`data_dir` 또는 `data_files` 매개 변수를 사용하여 데이터셋의 위치를 지정할 수 있습니다.
|
| 52 |
+
`data_files` 매개변수는 특정 파일을 `train` 이나 `test` 로 분리한 데이터셋에 매핑하는 것을 지원합니다:
|
| 53 |
+
|
| 54 |
+
```python
|
| 55 |
+
from datasets import load_dataset
|
| 56 |
+
|
| 57 |
+
# 예시 1: 로컬 폴더
|
| 58 |
+
dataset = load_dataset("imagefolder", data_dir="path_to_your_folder")
|
| 59 |
+
|
| 60 |
+
# 예시 2: 로컬 파일 (지원 포맷 : tar, gzip, zip, xz, rar, zstd)
|
| 61 |
+
dataset = load_dataset("imagefolder", data_files="path_to_zip_file")
|
| 62 |
+
|
| 63 |
+
# 예시 3: 원격 파일 (지원 포맷 : tar, gzip, zip, xz, rar, zstd)
|
| 64 |
+
dataset = load_dataset(
|
| 65 |
+
"imagefolder",
|
| 66 |
+
data_files="https://download.microsoft.com/download/3/E/1/3E1C3F21-ECDB-4869-8368-6DEBA77B919F/kagglecatsanddogs_3367a.zip",
|
| 67 |
+
)
|
| 68 |
+
|
| 69 |
+
# 예시 4: 여러개로 분할
|
| 70 |
+
dataset = load_dataset(
|
| 71 |
+
"imagefolder", data_files={"train": ["path/to/file1", "path/to/file2"], "test": ["path/to/file3", "path/to/file4"]}
|
| 72 |
+
)
|
| 73 |
+
```
|
| 74 |
+
|
| 75 |
+
[push_to_hub(https://huggingface.co/docs/datasets/v2.13.1/en/package_reference/main_classes#datasets.Dataset.push_to_hub) 을 사용해서 Hub에 데이터셋을 업로드 합니다:
|
| 76 |
+
|
| 77 |
+
```python
|
| 78 |
+
# 터미널에서 huggingface-cli login 커맨드를 이미 실행했다고 가정합니다
|
| 79 |
+
dataset.push_to_hub("name_of_your_dataset")
|
| 80 |
+
|
| 81 |
+
# 개인 repo로 push 하고 싶다면, `private=True` 을 추가하세요:
|
| 82 |
+
dataset.push_to_hub("name_of_your_dataset", private=True)
|
| 83 |
+
```
|
| 84 |
+
|
| 85 |
+
이제 데이터셋 이름을 `--dataset_name` 인수에 전달하여 데이터셋을 학습에 사용할 수 있습니다:
|
| 86 |
+
|
| 87 |
+
```bash
|
| 88 |
+
accelerate launch --mixed_precision="fp16" train_text_to_image.py \
|
| 89 |
+
--pretrained_model_name_or_path="stable-diffusion-v1-5/stable-diffusion-v1-5" \
|
| 90 |
+
--dataset_name="name_of_your_dataset" \
|
| 91 |
+
<other-arguments>
|
| 92 |
+
```
|
| 93 |
+
|
| 94 |
+
## 다음 단계
|
| 95 |
+
|
| 96 |
+
데이터셋을 생성했으니 이제 학습 스크립트의 `train_data_dir` (데이터셋이 로컬이면) 혹은 `dataset_name` (Hub에 데이터셋을 올렸으면) 인수에 연결할 수 있습니다.
|
| 97 |
+
|
| 98 |
+
다음 단계에서는 데이터셋을 사용하여 [unconditional 생성](https://huggingface.co/docs/diffusers/v0.18.2/en/training/unconditional_training) 또는 [텍스트-이미지 생성](https://huggingface.co/docs/diffusers/training/text2image)을 위한 모델을 학습시켜보세요!
|
tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/training/custom_diffusion.md
ADDED
|
@@ -0,0 +1,300 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2024 Custom Diffusion authors The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# 커스텀 Diffusion 학습 예제
|
| 14 |
+
|
| 15 |
+
[커스텀 Diffusion](https://huggingface.co/papers/2212.04488)은 피사체의 이미지 몇 장(4~5장)만 주어지면 Stable Diffusion처럼 text-to-image 모델을 커스터마이징하는 방법입니다.
|
| 16 |
+
'train_custom_diffusion.py' 스크립트는 학습 과정을 구현하고 이를 Stable Diffusion에 맞게 조정하는 방법을 보여줍니다.
|
| 17 |
+
|
| 18 |
+
이 교육 사례는 [Nupur Kumari](https://nupurkmr9.github.io/)가 제공하였습니다. (Custom Diffusion의 저자 중 한명).
|
| 19 |
+
|
| 20 |
+
## 로컬에서 PyTorch로 실행하기
|
| 21 |
+
|
| 22 |
+
### Dependencies 설치하기
|
| 23 |
+
|
| 24 |
+
스크립트를 실행하기 전에 라이브러리의 학습 dependencies를 설치해야 합니다:
|
| 25 |
+
|
| 26 |
+
**중요**
|
| 27 |
+
|
| 28 |
+
예제 스크립트의 최신 버전을 성공적으로 실행하려면 **소스로부터 설치**하는 것을 매우 권장하며, 예제 스크립트를 자주 업데이트하는 만큼 일부 예제별 요구 사항을 설치하고 설치를 최신 상태로 유지하는 것이 좋습니다. 이를 위해 새 가상 환경에서 다음 단계를 실행하세요:
|
| 29 |
+
|
| 30 |
+
|
| 31 |
+
```bash
|
| 32 |
+
git clone https://github.com/huggingface/diffusers
|
| 33 |
+
cd diffusers
|
| 34 |
+
pip install -e .
|
| 35 |
+
```
|
| 36 |
+
|
| 37 |
+
[example folder](https://github.com/huggingface/diffusers/tree/main/examples/custom_diffusion)로 cd하여 이동하세요.
|
| 38 |
+
|
| 39 |
+
```
|
| 40 |
+
cd examples/custom_diffusion
|
| 41 |
+
```
|
| 42 |
+
|
| 43 |
+
이제 실행
|
| 44 |
+
|
| 45 |
+
```bash
|
| 46 |
+
pip install -r requirements.txt
|
| 47 |
+
pip install clip-retrieval
|
| 48 |
+
```
|
| 49 |
+
|
| 50 |
+
그리고 [🤗Accelerate](https://github.com/huggingface/accelerate/) 환경을 초기화:
|
| 51 |
+
|
| 52 |
+
```bash
|
| 53 |
+
accelerate config
|
| 54 |
+
```
|
| 55 |
+
|
| 56 |
+
또는 사용자 환경에 대한 질문에 답하지 않고 기본 가속 구성을 사용하려면 다음과 같이 하세요.
|
| 57 |
+
|
| 58 |
+
```bash
|
| 59 |
+
accelerate config default
|
| 60 |
+
```
|
| 61 |
+
|
| 62 |
+
또는 사용 중인 환경이 대화형 셸을 지원하지 않는 경우(예: jupyter notebook)
|
| 63 |
+
|
| 64 |
+
```python
|
| 65 |
+
from accelerate.utils import write_basic_config
|
| 66 |
+
|
| 67 |
+
write_basic_config()
|
| 68 |
+
```
|
| 69 |
+
### 고양이 예제 😺
|
| 70 |
+
|
| 71 |
+
이제 데이터셋을 가져옵니다. [여기](https://www.cs.cmu.edu/~custom-diffusion/assets/data.zip)에서 데이터셋을 다운로드하고 압축을 풉니다. 직접 데이터셋을 사용하려면 [학습용 데이터셋 생성하기](create_dataset) 가이드를 참고하세요.
|
| 72 |
+
|
| 73 |
+
또한 'clip-retrieval'을 사용하여 200개의 실제 이미지를 수집하고, regularization으로서 이를 학습 데이터셋의 타겟 이미지와 결합합니다. 이렇게 하면 주어진 타겟 이미지에 대한 과적합을 방지할 수 있습니다. 다음 플래그를 사용하면 `prior_loss_weight=1.`로 `prior_preservation`, `real_prior` regularization을 활성화할 수 있습니다.
|
| 74 |
+
클래스_프롬프트`는 대상 이미지와 동일한 카테고리 이름이어야 합니다. 수집된 실제 이미지에는 `class_prompt`와 유사한 텍스트 캡션이 있습니다. 검색된 이미지는 `class_data_dir`에 저장됩니다. 생성된 이미지를 regularization으로 사용하기 위해 `real_prior`를 비활성화할 수 있습니다. 실제 이미지를 수집하려면 훈련 전에 이 명령을 먼저 사용하십시오.
|
| 75 |
+
|
| 76 |
+
```bash
|
| 77 |
+
pip install clip-retrieval
|
| 78 |
+
python retrieve.py --class_prompt cat --class_data_dir real_reg/samples_cat --num_class_images 200
|
| 79 |
+
```
|
| 80 |
+
|
| 81 |
+
**___참고: [stable-diffusion-2](https://huggingface.co/stabilityai/stable-diffusion-2) 768x768 모델을 사용하는 경우 '해상도'를 768로 변경하세요.___**
|
| 82 |
+
|
| 83 |
+
스크립트는 모델 체크포인트와 `pytorch_custom_diffusion_weights.bin` 파일을 생성하여 저장소에 저장합니다.
|
| 84 |
+
|
| 85 |
+
```bash
|
| 86 |
+
export MODEL_NAME="CompVis/stable-diffusion-v1-4"
|
| 87 |
+
export OUTPUT_DIR="path-to-save-model"
|
| 88 |
+
export INSTANCE_DIR="./data/cat"
|
| 89 |
+
|
| 90 |
+
accelerate launch train_custom_diffusion.py \
|
| 91 |
+
--pretrained_model_name_or_path=$MODEL_NAME \
|
| 92 |
+
--instance_data_dir=$INSTANCE_DIR \
|
| 93 |
+
--output_dir=$OUTPUT_DIR \
|
| 94 |
+
--class_data_dir=./real_reg/samples_cat/ \
|
| 95 |
+
--with_prior_preservation --real_prior --prior_loss_weight=1.0 \
|
| 96 |
+
--class_prompt="cat" --num_class_images=200 \
|
| 97 |
+
--instance_prompt="photo of a <new1> cat" \
|
| 98 |
+
--resolution=512 \
|
| 99 |
+
--train_batch_size=2 \
|
| 100 |
+
--learning_rate=1e-5 \
|
| 101 |
+
--lr_warmup_steps=0 \
|
| 102 |
+
--max_train_steps=250 \
|
| 103 |
+
--scale_lr --hflip \
|
| 104 |
+
--modifier_token "<new1>" \
|
| 105 |
+
--push_to_hub
|
| 106 |
+
```
|
| 107 |
+
|
| 108 |
+
**더 낮은 VRAM 요구 사항(GPU당 16GB)으로 더 빠르게 훈련하려면 `--enable_xformers_memory_efficient_attention`을 사��하세요. 설치 방법은 [가이드](https://github.com/facebookresearch/xformers)를 따르세요.**
|
| 109 |
+
|
| 110 |
+
가중치 및 편향(`wandb`)을 사용하여 실험을 추적하고 중간 결과를 저장하려면(강력히 권장합니다) 다음 단계를 따르세요:
|
| 111 |
+
|
| 112 |
+
* `wandb` 설치: `pip install wandb`.
|
| 113 |
+
* 로그인 : `wandb login`.
|
| 114 |
+
* 그런 다음 트레이닝을 시작하는 동안 `validation_prompt`를 지정하고 `report_to`를 `wandb`로 설정합니다. 다음과 같은 관련 인수를 구성할 수도 있습니다:
|
| 115 |
+
* `num_validation_images`
|
| 116 |
+
* `validation_steps`
|
| 117 |
+
|
| 118 |
+
```bash
|
| 119 |
+
accelerate launch train_custom_diffusion.py \
|
| 120 |
+
--pretrained_model_name_or_path=$MODEL_NAME \
|
| 121 |
+
--instance_data_dir=$INSTANCE_DIR \
|
| 122 |
+
--output_dir=$OUTPUT_DIR \
|
| 123 |
+
--class_data_dir=./real_reg/samples_cat/ \
|
| 124 |
+
--with_prior_preservation --real_prior --prior_loss_weight=1.0 \
|
| 125 |
+
--class_prompt="cat" --num_class_images=200 \
|
| 126 |
+
--instance_prompt="photo of a <new1> cat" \
|
| 127 |
+
--resolution=512 \
|
| 128 |
+
--train_batch_size=2 \
|
| 129 |
+
--learning_rate=1e-5 \
|
| 130 |
+
--lr_warmup_steps=0 \
|
| 131 |
+
--max_train_steps=250 \
|
| 132 |
+
--scale_lr --hflip \
|
| 133 |
+
--modifier_token "<new1>" \
|
| 134 |
+
--validation_prompt="<new1> cat sitting in a bucket" \
|
| 135 |
+
--report_to="wandb" \
|
| 136 |
+
--push_to_hub
|
| 137 |
+
```
|
| 138 |
+
|
| 139 |
+
다음은 [Weights and Biases page](https://wandb.ai/sayakpaul/custom-diffusion/runs/26ghrcau)의 예시이며, 여러 학습 세부 정보와 함께 중간 결과들을 확인할 수 있습니다.
|
| 140 |
+
|
| 141 |
+
`--push_to_hub`를 지정하면 학습된 파라미터가 허깅 페이스 허브의 리포지토리에 푸시됩니다. 다음은 [예제 리포지토리](https://huggingface.co/sayakpaul/custom-diffusion-cat)입니다.
|
| 142 |
+
|
| 143 |
+
### 멀티 컨셉에 대한 학습 🐱🪵
|
| 144 |
+
|
| 145 |
+
[this](https://github.com/ShivamShrirao/diffusers/blob/main/examples/dreambooth/train_dreambooth.py)와 유사하게 각 컨셉에 대한 정보가 포함된 [json](https://github.com/adobe-research/custom-diffusion/blob/main/assets/concept_list.json) 파일을 제공합니다.
|
| 146 |
+
|
| 147 |
+
실제 이미지를 수집하려면 json 파일의 각 컨셉에 대해 이 명령을 실행합니다.
|
| 148 |
+
|
| 149 |
+
```bash
|
| 150 |
+
pip install clip-retrieval
|
| 151 |
+
python retrieve.py --class_prompt {} --class_data_dir {} --num_class_images 200
|
| 152 |
+
```
|
| 153 |
+
|
| 154 |
+
그럼 우리는 학습시킬 준비가 되었습니다!
|
| 155 |
+
|
| 156 |
+
```bash
|
| 157 |
+
export MODEL_NAME="CompVis/stable-diffusion-v1-4"
|
| 158 |
+
export OUTPUT_DIR="path-to-save-model"
|
| 159 |
+
|
| 160 |
+
accelerate launch train_custom_diffusion.py \
|
| 161 |
+
--pretrained_model_name_or_path=$MODEL_NAME \
|
| 162 |
+
--output_dir=$OUTPUT_DIR \
|
| 163 |
+
--concepts_list=./concept_list.json \
|
| 164 |
+
--with_prior_preservation --real_prior --prior_loss_weight=1.0 \
|
| 165 |
+
--resolution=512 \
|
| 166 |
+
--train_batch_size=2 \
|
| 167 |
+
--learning_rate=1e-5 \
|
| 168 |
+
--lr_warmup_steps=0 \
|
| 169 |
+
--max_train_steps=500 \
|
| 170 |
+
--num_class_images=200 \
|
| 171 |
+
--scale_lr --hflip \
|
| 172 |
+
--modifier_token "<new1>+<new2>" \
|
| 173 |
+
--push_to_hub
|
| 174 |
+
```
|
| 175 |
+
|
| 176 |
+
다음은 [Weights and Biases page](https://wandb.ai/sayakpaul/custom-diffusion/runs/3990tzkg)의 예시이며, 다른 학습 세부 정보와 함께 중간 결과들을 확인할 수 있습니다.
|
| 177 |
+
|
| 178 |
+
### 사람 얼굴에 대한 학습
|
| 179 |
+
|
| 180 |
+
사람 얼굴에 대한 파인튜닝을 위해 다음과 같은 설정이 더 효과적이라는 것을 확인했습니다: `learning_rate=5e-6`, `max_train_steps=1000 to 2000`, `freeze_model=crossattn`을 최소 15~20개의 이미지로 설정합니다.
|
| 181 |
+
|
| 182 |
+
실제 이미지를 수집하려면 훈련 전에 이 명령을 먼저 사용하십시오.
|
| 183 |
+
|
| 184 |
+
```bash
|
| 185 |
+
pip install clip-retrieval
|
| 186 |
+
python retrieve.py --class_prompt person --class_data_dir real_reg/samples_person --num_class_images 200
|
| 187 |
+
```
|
| 188 |
+
|
| 189 |
+
이제 학습을 시작하세요!
|
| 190 |
+
|
| 191 |
+
```bash
|
| 192 |
+
export MODEL_NAME="CompVis/stable-diffusion-v1-4"
|
| 193 |
+
export OUTPUT_DIR="path-to-save-model"
|
| 194 |
+
export INSTANCE_DIR="path-to-images"
|
| 195 |
+
|
| 196 |
+
accelerate launch train_custom_diffusion.py \
|
| 197 |
+
--pretrained_model_name_or_path=$MODEL_NAME \
|
| 198 |
+
--instance_data_dir=$INSTANCE_DIR \
|
| 199 |
+
--output_dir=$OUTPUT_DIR \
|
| 200 |
+
--class_data_dir=./real_reg/samples_person/ \
|
| 201 |
+
--with_prior_preservation --real_prior --prior_loss_weight=1.0 \
|
| 202 |
+
--class_prompt="person" --num_class_images=200 \
|
| 203 |
+
--instance_prompt="photo of a <new1> person" \
|
| 204 |
+
--resolution=512 \
|
| 205 |
+
--train_batch_size=2 \
|
| 206 |
+
--learning_rate=5e-6 \
|
| 207 |
+
--lr_warmup_steps=0 \
|
| 208 |
+
--max_train_steps=1000 \
|
| 209 |
+
--scale_lr --hflip --noaug \
|
| 210 |
+
--freeze_model crossattn \
|
| 211 |
+
--modifier_token "<new1>" \
|
| 212 |
+
--enable_xformers_memory_efficient_attention \
|
| 213 |
+
--push_to_hub
|
| 214 |
+
```
|
| 215 |
+
|
| 216 |
+
## 추론
|
| 217 |
+
|
| 218 |
+
위 프롬프트를 사용하여 모델을 학습시킨 후에는 아래 프롬프트를 사용하여 추론을 실행할 수 있습니다. 프롬프트에 'modifier token'(예: 위 예제에서는 \<new1\>)을 반드시 포함해야 합니다.
|
| 219 |
+
|
| 220 |
+
```python
|
| 221 |
+
import torch
|
| 222 |
+
from diffusers import DiffusionPipeline
|
| 223 |
+
|
| 224 |
+
pipe = DiffusionPipeline.from_pretrained("CompVis/stable-diffusion-v1-4", torch_dtype=torch.float16).to("cuda")
|
| 225 |
+
pipe.unet.load_attn_procs("path-to-save-model", weight_name="pytorch_custom_diffusion_weights.bin")
|
| 226 |
+
pipe.load_textual_inversion("path-to-save-model", weight_name="<new1>.bin")
|
| 227 |
+
|
| 228 |
+
image = pipe(
|
| 229 |
+
"<new1> cat sitting in a bucket",
|
| 230 |
+
num_inference_steps=100,
|
| 231 |
+
guidance_scale=6.0,
|
| 232 |
+
eta=1.0,
|
| 233 |
+
).images[0]
|
| 234 |
+
image.save("cat.png")
|
| 235 |
+
```
|
| 236 |
+
|
| 237 |
+
허브 리포지토리에서 이러한 매개변수를 직접 로드할 수 있습니다:
|
| 238 |
+
|
| 239 |
+
```python
|
| 240 |
+
import torch
|
| 241 |
+
from huggingface_hub.repocard import RepoCard
|
| 242 |
+
from diffusers import DiffusionPipeline
|
| 243 |
+
|
| 244 |
+
model_id = "sayakpaul/custom-diffusion-cat"
|
| 245 |
+
card = RepoCard.load(model_id)
|
| 246 |
+
base_model_id = card.data.to_dict()["base_model"]
|
| 247 |
+
|
| 248 |
+
pipe = DiffusionPipeline.from_pretrained(base_model_id, torch_dtype=torch.float16).to("cuda")
|
| 249 |
+
pipe.unet.load_attn_procs(model_id, weight_name="pytorch_custom_diffusion_weights.bin")
|
| 250 |
+
pipe.load_textual_inversion(model_id, weight_name="<new1>.bin")
|
| 251 |
+
|
| 252 |
+
image = pipe(
|
| 253 |
+
"<new1> cat sitting in a bucket",
|
| 254 |
+
num_inference_steps=100,
|
| 255 |
+
guidance_scale=6.0,
|
| 256 |
+
eta=1.0,
|
| 257 |
+
).images[0]
|
| 258 |
+
image.save("cat.png")
|
| 259 |
+
```
|
| 260 |
+
|
| 261 |
+
다음은 여러 컨셉으로 추론을 수행하는 예제입니다:
|
| 262 |
+
|
| 263 |
+
```python
|
| 264 |
+
import torch
|
| 265 |
+
from huggingface_hub.repocard import RepoCard
|
| 266 |
+
from diffusers import DiffusionPipeline
|
| 267 |
+
|
| 268 |
+
model_id = "sayakpaul/custom-diffusion-cat-wooden-pot"
|
| 269 |
+
card = RepoCard.load(model_id)
|
| 270 |
+
base_model_id = card.data.to_dict()["base_model"]
|
| 271 |
+
|
| 272 |
+
pipe = DiffusionPipeline.from_pretrained(base_model_id, torch_dtype=torch.float16).to("cuda")
|
| 273 |
+
pipe.unet.load_attn_procs(model_id, weight_name="pytorch_custom_diffusion_weights.bin")
|
| 274 |
+
pipe.load_textual_inversion(model_id, weight_name="<new1>.bin")
|
| 275 |
+
pipe.load_textual_inversion(model_id, weight_name="<new2>.bin")
|
| 276 |
+
|
| 277 |
+
image = pipe(
|
| 278 |
+
"the <new1> cat sculpture in the style of a <new2> wooden pot",
|
| 279 |
+
num_inference_steps=100,
|
| 280 |
+
guidance_scale=6.0,
|
| 281 |
+
eta=1.0,
|
| 282 |
+
).images[0]
|
| 283 |
+
image.save("multi-subject.png")
|
| 284 |
+
```
|
| 285 |
+
|
| 286 |
+
여기서 '고양이'와 '나무 냄비'는 여러 컨셉을 말합니다.
|
| 287 |
+
|
| 288 |
+
### 학습된 체크포인트에서 추론하기
|
| 289 |
+
|
| 290 |
+
`--checkpointing_steps` 인수를 사용한 경우 학습 과정에서 저장된 전체 체크포인트 중 하나에서 추론을 수행할 수도 있습니다.
|
| 291 |
+
|
| 292 |
+
## Grads를 None으로 설정
|
| 293 |
+
|
| 294 |
+
더 많은 메모리를 절약하려면 스크립트에 `--set_grads_to_none` 인수를 전달하세요. 이렇게 하면 성적이 0이 아닌 없음으로 설정됩니다. 그러나 특정 동작이 변경되므로 문제가 발생하면 이 인수를 제거하세요.
|
| 295 |
+
|
| 296 |
+
자세한 정보: https://pytorch.org/docs/stable/generated/torch.optim.Optimizer.zero_grad.html
|
| 297 |
+
|
| 298 |
+
## 실험 결과
|
| 299 |
+
|
| 300 |
+
실험에 대한 자세한 내용은 [당사 웹페이지](https://www.cs.cmu.edu/~custom-diffusion/)를 참조하세요.
|
tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/training/distributed_inference.md
ADDED
|
@@ -0,0 +1,92 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# 여러 GPU를 사용한 분산 추론
|
| 2 |
+
|
| 3 |
+
분산 설정에서는 여러 개의 프롬프트를 동시에 생성할 때 유용한 🤗 [Accelerate](https://huggingface.co/docs/accelerate/index) 또는 [PyTorch Distributed](https://pytorch.org/tutorials/beginner/dist_overview.html)를 사용하여 여러 GPU에서 추론을 실행할 수 있습니다.
|
| 4 |
+
|
| 5 |
+
이 가이드에서는 분산 추론을 위해 🤗 Accelerate와 PyTorch Distributed를 사용하는 방법을 보여드립니다.
|
| 6 |
+
|
| 7 |
+
## 🤗 Accelerate
|
| 8 |
+
|
| 9 |
+
🤗 [Accelerate](https://huggingface.co/docs/accelerate/index)는 분산 설정에서 추론을 쉽게 훈련하거나 실행할 수 있도록 설계된 라이브러리입니다. 분산 환경 설정 프로세스를 간소화하여 PyTorch 코드에 집중할 수 있도록 해줍니다.
|
| 10 |
+
|
| 11 |
+
시작하려면 Python 파일을 생성하고 [`accelerate.PartialState`]를 초기화하여 분산 환경을 생성하면, 설정이 자동으로 감지되므로 `rank` 또는 `world_size`를 명시적으로 정의할 필요가 없습니다. ['DiffusionPipeline`]을 `distributed_state.device`로 이동하여 각 프로세스에 GPU를 할당합니다.
|
| 12 |
+
|
| 13 |
+
이제 컨텍스트 관리자로 [`~accelerate.PartialState.split_between_processes`] 유틸리티를 사용하여 프로세스 수에 따라 프롬프트를 자동으로 분배합니다.
|
| 14 |
+
|
| 15 |
+
|
| 16 |
+
```py
|
| 17 |
+
from accelerate import PartialState
|
| 18 |
+
from diffusers import DiffusionPipeline
|
| 19 |
+
|
| 20 |
+
pipeline = DiffusionPipeline.from_pretrained("stable-diffusion-v1-5/stable-diffusion-v1-5", torch_dtype=torch.float16)
|
| 21 |
+
distributed_state = PartialState()
|
| 22 |
+
pipeline.to(distributed_state.device)
|
| 23 |
+
|
| 24 |
+
with distributed_state.split_between_processes(["a dog", "a cat"]) as prompt:
|
| 25 |
+
result = pipeline(prompt).images[0]
|
| 26 |
+
result.save(f"result_{distributed_state.process_index}.png")
|
| 27 |
+
```
|
| 28 |
+
|
| 29 |
+
Use the `--num_processes` argument to specify the number of GPUs to use, and call `accelerate launch` to run the script:
|
| 30 |
+
|
| 31 |
+
```bash
|
| 32 |
+
accelerate launch run_distributed.py --num_processes=2
|
| 33 |
+
```
|
| 34 |
+
|
| 35 |
+
<Tip>자세한 내용은 [🤗 Accelerate를 사용한 분산 추론](https://huggingface.co/docs/accelerate/en/usage_guides/distributed_inference#distributed-inference-with-accelerate) 가이드를 참조하세요.
|
| 36 |
+
|
| 37 |
+
</Tip>
|
| 38 |
+
|
| 39 |
+
## Pytoerch 분산
|
| 40 |
+
|
| 41 |
+
PyTorch는 데이터 병렬 처리를 가능하게 하는 [`DistributedDataParallel`](https://pytorch.org/docs/stable/generated/torch.nn.parallel.DistributedDataParallel.html)을 지원합니다.
|
| 42 |
+
|
| 43 |
+
시작하려면 Python 파일을 생성하고 `torch.distributed` 및 `torch.multiprocessing`을 임포트하여 분산 프로세스 그룹을 설정하고 각 GPU에서 추론용 프로세스를 생성합니다. 그리고 [`DiffusionPipeline`]도 초기화해야 합니다:
|
| 44 |
+
|
| 45 |
+
확산 파이프라인을 `rank`로 이동하고 `get_rank`를 사용하여 각 프로세스에 GPU를 할당하면 각 프로세스가 다른 프롬프트를 처리합니다:
|
| 46 |
+
|
| 47 |
+
```py
|
| 48 |
+
import torch
|
| 49 |
+
import torch.distributed as dist
|
| 50 |
+
import torch.multiprocessing as mp
|
| 51 |
+
|
| 52 |
+
from diffusers import DiffusionPipeline
|
| 53 |
+
|
| 54 |
+
sd = DiffusionPipeline.from_pretrained("stable-diffusion-v1-5/stable-diffusion-v1-5", torch_dtype=torch.float16)
|
| 55 |
+
```
|
| 56 |
+
|
| 57 |
+
사용할 백엔드 유형, 현재 프로세스의 `rank`, `world_size` 또는 참여하는 프로세스 수로 분산 환경 생성을 처리하는 함수[`init_process_group`]를 만들어 추론을 실행해야 합니다.
|
| 58 |
+
|
| 59 |
+
2개의 GPU에서 추론을 병렬로 실행하는 경우 `world_size`는 2입니다.
|
| 60 |
+
|
| 61 |
+
```py
|
| 62 |
+
def run_inference(rank, world_size):
|
| 63 |
+
dist.init_process_group("nccl", rank=rank, world_size=world_size)
|
| 64 |
+
|
| 65 |
+
sd.to(rank)
|
| 66 |
+
|
| 67 |
+
if torch.distributed.get_rank() == 0:
|
| 68 |
+
prompt = "a dog"
|
| 69 |
+
elif torch.distributed.get_rank() == 1:
|
| 70 |
+
prompt = "a cat"
|
| 71 |
+
|
| 72 |
+
image = sd(prompt).images[0]
|
| 73 |
+
image.save(f"./{'_'.join(prompt)}.png")
|
| 74 |
+
```
|
| 75 |
+
|
| 76 |
+
분산 추론을 실행하려면 [`mp.spawn`](https://pytorch.org/docs/stable/multiprocessing.html#torch.multiprocessing.spawn)을 호출하여 `world_size`에 정의된 GPU 수에 대해 `run_inference` 함수를 실행합니다:
|
| 77 |
+
|
| 78 |
+
```py
|
| 79 |
+
def main():
|
| 80 |
+
world_size = 2
|
| 81 |
+
mp.spawn(run_inference, args=(world_size,), nprocs=world_size, join=True)
|
| 82 |
+
|
| 83 |
+
|
| 84 |
+
if __name__ == "__main__":
|
| 85 |
+
main()
|
| 86 |
+
```
|
| 87 |
+
|
| 88 |
+
추론 스크립트를 완료했으면 `--nproc_per_node` 인수를 사용하여 사용할 GPU 수를 지정하고 `torchrun`을 호출하여 스크립트를 실행합니다:
|
| 89 |
+
|
| 90 |
+
```bash
|
| 91 |
+
torchrun run_distributed.py --nproc_per_node=2
|
| 92 |
+
```
|
tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/training/dreambooth.md
ADDED
|
@@ -0,0 +1,474 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2024 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# DreamBooth
|
| 14 |
+
|
| 15 |
+
[DreamBooth](https://huggingface.co/papers/2208.12242)는 한 주제에 대한 적은 이미지(3~5개)만으로도 stable diffusion과 같이 text-to-image 모델을 개인화할 수 있는 방법입니다. 이를 통해 모델은 다양한 장면, 포즈 및 장면(뷰)에서 피사체에 대해 맥락화(contextualized)된 이미지를 생성할 수 있습니다.
|
| 16 |
+
|
| 17 |
+
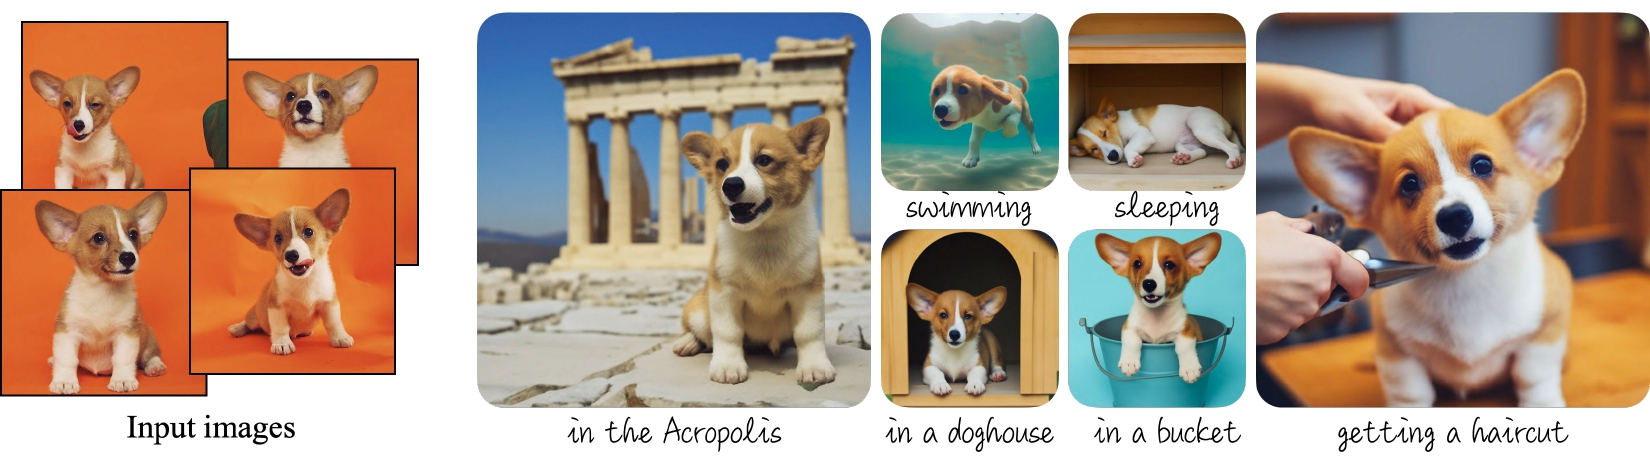
|
| 18 |
+
<small>에서의 Dreambooth 예시 <a href="https://dreambooth.github.io">project's blog.</a></small>
|
| 19 |
+
|
| 20 |
+
|
| 21 |
+
이 가이드는 다양한 GPU, Flax 사양에 대해 [`CompVis/stable-diffusion-v1-4`](https://huggingface.co/CompVis/stable-diffusion-v1-4) 모델로 DreamBooth를 파인튜닝하는 방법을 보여줍니다. 더 깊이 파고들어 작동 방식을 확인하는 데 관심이 있는 경우, 이 가이드에 사용된 DreamBooth의 모든 학습 스크립트를 [여기](https://github.com/huggingface/diffusers/tree/main/examples/dreambooth)에서 찾을 수 있습니다.
|
| 22 |
+
|
| 23 |
+
스크립트를 실행하기 전에 라이브러리의 학습에 필요한 dependencies를 설치해야 합니다. 또한 `main` GitHub 브랜치에서 🧨 Diffusers를 설치하는 것이 좋습니다.
|
| 24 |
+
|
| 25 |
+
```bash
|
| 26 |
+
pip install git+https://github.com/huggingface/diffusers
|
| 27 |
+
pip install -U -r diffusers/examples/dreambooth/requirements.txt
|
| 28 |
+
```
|
| 29 |
+
|
| 30 |
+
xFormers는 학습에 필요한 요구 사항은 아니지만, 가능하면 [설치](../optimization/xformers)하는 것이 좋습니다. 학습 속도를 높이고 메모리 사용량을 줄일 수 있기 때문입니다.
|
| 31 |
+
|
| 32 |
+
모든 dependencies을 설정한 후 다음을 사용하여 [🤗 Accelerate](https://github.com/huggingface/accelerate/) 환경을 다음과 같이 초기화합니다:
|
| 33 |
+
|
| 34 |
+
```bash
|
| 35 |
+
accelerate config
|
| 36 |
+
```
|
| 37 |
+
|
| 38 |
+
별도 설정 없이 기본 🤗 Accelerate 환경을 설치하려면 다음을 실행합니다:
|
| 39 |
+
|
| 40 |
+
```bash
|
| 41 |
+
accelerate config default
|
| 42 |
+
```
|
| 43 |
+
|
| 44 |
+
또는 현재 환경이 노트북과 같은 대화형 셸을 지원하지 않는 경우 다음을 사용할 수 있습니다:
|
| 45 |
+
|
| 46 |
+
```py
|
| 47 |
+
from accelerate.utils import write_basic_config
|
| 48 |
+
|
| 49 |
+
write_basic_config()
|
| 50 |
+
```
|
| 51 |
+
|
| 52 |
+
## 파인튜닝
|
| 53 |
+
|
| 54 |
+
<Tip warning={true}>
|
| 55 |
+
|
| 56 |
+
DreamBooth 파인튜닝은 하이퍼파라미터에 매우 민감하고 과적합되기 쉽습니다. 적절한 하이퍼파라미터를 선택하는 데 도움이 되도록 다양한 권장 설정이 포함된 [심층 분석](https://huggingface.co/blog/dreambooth)을 살펴보는 것이 좋습니다.
|
| 57 |
+
|
| 58 |
+
</Tip>
|
| 59 |
+
|
| 60 |
+
<frameworkcontent>
|
| 61 |
+
<pt>
|
| 62 |
+
[몇 장의 강아지 이미지들](https://drive.google.com/drive/folders/1BO_dyz-p65qhBRRMRA4TbZ8qW4rB99JZ)로 DreamBooth를 시도해봅시다.
|
| 63 |
+
이를 다운로드해 디렉터리에 저장한 다음 `INSTANCE_DIR` 환경 변수를 해당 경로로 설정합니다:
|
| 64 |
+
|
| 65 |
+
|
| 66 |
+
```bash
|
| 67 |
+
export MODEL_NAME="CompVis/stable-diffusion-v1-4"
|
| 68 |
+
export INSTANCE_DIR="path_to_training_images"
|
| 69 |
+
export OUTPUT_DIR="path_to_saved_model"
|
| 70 |
+
```
|
| 71 |
+
|
| 72 |
+
그런 다음, 다음 명령을 사용하여 학습 스크립트를 실행할 수 있습니다 (전체 학습 스크립트는 [여기](https://github.com/huggingface/diffusers/blob/main/examples/dreambooth/train_dreambooth.py)에서 찾을 수 있습니다):
|
| 73 |
+
|
| 74 |
+
```bash
|
| 75 |
+
accelerate launch train_dreambooth.py \
|
| 76 |
+
--pretrained_model_name_or_path=$MODEL_NAME \
|
| 77 |
+
--instance_data_dir=$INSTANCE_DIR \
|
| 78 |
+
--output_dir=$OUTPUT_DIR \
|
| 79 |
+
--instance_prompt="a photo of sks dog" \
|
| 80 |
+
--resolution=512 \
|
| 81 |
+
--train_batch_size=1 \
|
| 82 |
+
--gradient_accumulation_steps=1 \
|
| 83 |
+
--learning_rate=5e-6 \
|
| 84 |
+
--lr_scheduler="constant" \
|
| 85 |
+
--lr_warmup_steps=0 \
|
| 86 |
+
--max_train_steps=400
|
| 87 |
+
```
|
| 88 |
+
</pt>
|
| 89 |
+
<jax>
|
| 90 |
+
|
| 91 |
+
TPU에 액세스할 수 있거나 더 빠르게 훈련하고 싶다면 [Flax 학습 스크립트](https://github.com/huggingface/diffusers/blob/main/examples/dreambooth/train_dreambooth_flax.py)를 사용해 볼 수 있습니다. Flax 학습 스크립트는 gradient checkpointing 또는 gradient accumulation을 지원하지 않으므로, 메모리가 30GB 이상인 GPU가 필요합니다.
|
| 92 |
+
|
| 93 |
+
스크립트를 실행하기 전에 요구 사항이 설치되어 있는지 확인하십시오.
|
| 94 |
+
|
| 95 |
+
```bash
|
| 96 |
+
pip install -U -r requirements.txt
|
| 97 |
+
```
|
| 98 |
+
|
| 99 |
+
그러면 다음 명령어로 학습 스크립트를 실행시킬 수 있습니다:
|
| 100 |
+
|
| 101 |
+
```bash
|
| 102 |
+
export MODEL_NAME="duongna/stable-diffusion-v1-4-flax"
|
| 103 |
+
export INSTANCE_DIR="path-to-instance-images"
|
| 104 |
+
export OUTPUT_DIR="path-to-save-model"
|
| 105 |
+
|
| 106 |
+
python train_dreambooth_flax.py \
|
| 107 |
+
--pretrained_model_name_or_path=$MODEL_NAME \
|
| 108 |
+
--instance_data_dir=$INSTANCE_DIR \
|
| 109 |
+
--output_dir=$OUTPUT_DIR \
|
| 110 |
+
--instance_prompt="a photo of sks dog" \
|
| 111 |
+
--resolution=512 \
|
| 112 |
+
--train_batch_size=1 \
|
| 113 |
+
--learning_rate=5e-6 \
|
| 114 |
+
--max_train_steps=400
|
| 115 |
+
```
|
| 116 |
+
</jax>
|
| 117 |
+
</frameworkcontent>
|
| 118 |
+
|
| 119 |
+
### Prior-preserving(사전 보존) loss를 사용한 파인튜닝
|
| 120 |
+
|
| 121 |
+
과적합과 language drift를 방지하기 위해 사전 보존이 사용됩니다(관심이 있는 경우 [논문](https://huggingface.co/papers/2208.12242)을 참조하세요). 사전 보존을 위해 동일한 클래스의 다른 이미지를 학습 프로세스의 일부로 사용합니다. 좋은 점은 Stable Diffusion 모델 자체를 사용하여 이러한 이미지를 생성할 수 있다는 것입니다! 학습 스크립트는 생성된 이미지를 우리가 지정한 로컬 경로에 저장합니다.
|
| 122 |
+
|
| 123 |
+
저자들에 따르면 사전 보존을 위해 `num_epochs * num_samples`개의 이미지를 생성하는 것이 좋습니다. 200-300개에서 대부분 잘 작동합니다.
|
| 124 |
+
|
| 125 |
+
<frameworkcontent>
|
| 126 |
+
<pt>
|
| 127 |
+
```bash
|
| 128 |
+
export MODEL_NAME="CompVis/stable-diffusion-v1-4"
|
| 129 |
+
export INSTANCE_DIR="path_to_training_images"
|
| 130 |
+
export CLASS_DIR="path_to_class_images"
|
| 131 |
+
export OUTPUT_DIR="path_to_saved_model"
|
| 132 |
+
|
| 133 |
+
accelerate launch train_dreambooth.py \
|
| 134 |
+
--pretrained_model_name_or_path=$MODEL_NAME \
|
| 135 |
+
--instance_data_dir=$INSTANCE_DIR \
|
| 136 |
+
--class_data_dir=$CLASS_DIR \
|
| 137 |
+
--output_dir=$OUTPUT_DIR \
|
| 138 |
+
--with_prior_preservation --prior_loss_weight=1.0 \
|
| 139 |
+
--instance_prompt="a photo of sks dog" \
|
| 140 |
+
--class_prompt="a photo of dog" \
|
| 141 |
+
--resolution=512 \
|
| 142 |
+
--train_batch_size=1 \
|
| 143 |
+
--gradient_accumulation_steps=1 \
|
| 144 |
+
--learning_rate=5e-6 \
|
| 145 |
+
--lr_scheduler="constant" \
|
| 146 |
+
--lr_warmup_steps=0 \
|
| 147 |
+
--num_class_images=200 \
|
| 148 |
+
--max_train_steps=800
|
| 149 |
+
```
|
| 150 |
+
</pt>
|
| 151 |
+
<jax>
|
| 152 |
+
```bash
|
| 153 |
+
export MODEL_NAME="duongna/stable-diffusion-v1-4-flax"
|
| 154 |
+
export INSTANCE_DIR="path-to-instance-images"
|
| 155 |
+
export CLASS_DIR="path-to-class-images"
|
| 156 |
+
export OUTPUT_DIR="path-to-save-model"
|
| 157 |
+
|
| 158 |
+
python train_dreambooth_flax.py \
|
| 159 |
+
--pretrained_model_name_or_path=$MODEL_NAME \
|
| 160 |
+
--instance_data_dir=$INSTANCE_DIR \
|
| 161 |
+
--class_data_dir=$CLASS_DIR \
|
| 162 |
+
--output_dir=$OUTPUT_DIR \
|
| 163 |
+
--with_prior_preservation --prior_loss_weight=1.0 \
|
| 164 |
+
--instance_prompt="a photo of sks dog" \
|
| 165 |
+
--class_prompt="a photo of dog" \
|
| 166 |
+
--resolution=512 \
|
| 167 |
+
--train_batch_size=1 \
|
| 168 |
+
--learning_rate=5e-6 \
|
| 169 |
+
--num_class_images=200 \
|
| 170 |
+
--max_train_steps=800
|
| 171 |
+
```
|
| 172 |
+
</jax>
|
| 173 |
+
</frameworkcontent>
|
| 174 |
+
|
| 175 |
+
## 텍스트 인코더와 and UNet로 파인튜닝하기
|
| 176 |
+
|
| 177 |
+
해당 스크립트를 사용하면 `unet`과 함께 `text_encoder`를 파인튜닝할 수 있습니다. 실험에서(자세한 내용은 [🧨 Diffusers를 사용해 DreamBooth로 Stable Diffusion 학습하기](https://huggingface.co/blog/dreambooth) 게시물을 확인하세요), 특히 얼굴 이미지를 생성할 때 훨씬 더 나은 결과를 얻을 수 있습니다.
|
| 178 |
+
|
| 179 |
+
<Tip warning={true}>
|
| 180 |
+
|
| 181 |
+
텍스트 인코더를 학습시키려면 추가 메모리가 필요해 16GB GPU로는 동작하지 않습니다. 이 옵션을 사용하려면 최소 24GB VRAM이 필요합니다.
|
| 182 |
+
|
| 183 |
+
</Tip>
|
| 184 |
+
|
| 185 |
+
`--train_text_encoder` 인수를 학습 스크립트에 전달하여 `text_encoder` 및 `unet`을 파인튜닝할 수 있습니다:
|
| 186 |
+
|
| 187 |
+
<frameworkcontent>
|
| 188 |
+
<pt>
|
| 189 |
+
```bash
|
| 190 |
+
export MODEL_NAME="CompVis/stable-diffusion-v1-4"
|
| 191 |
+
export INSTANCE_DIR="path_to_training_images"
|
| 192 |
+
export CLASS_DIR="path_to_class_images"
|
| 193 |
+
export OUTPUT_DIR="path_to_saved_model"
|
| 194 |
+
|
| 195 |
+
accelerate launch train_dreambooth.py \
|
| 196 |
+
--pretrained_model_name_or_path=$MODEL_NAME \
|
| 197 |
+
--train_text_encoder \
|
| 198 |
+
--instance_data_dir=$INSTANCE_DIR \
|
| 199 |
+
--class_data_dir=$CLASS_DIR \
|
| 200 |
+
--output_dir=$OUTPUT_DIR \
|
| 201 |
+
--with_prior_preservation --prior_loss_weight=1.0 \
|
| 202 |
+
--instance_prompt="a photo of sks dog" \
|
| 203 |
+
--class_prompt="a photo of dog" \
|
| 204 |
+
--resolution=512 \
|
| 205 |
+
--train_batch_size=1 \
|
| 206 |
+
--use_8bit_adam
|
| 207 |
+
--gradient_checkpointing \
|
| 208 |
+
--learning_rate=2e-6 \
|
| 209 |
+
--lr_scheduler="constant" \
|
| 210 |
+
--lr_warmup_steps=0 \
|
| 211 |
+
--num_class_images=200 \
|
| 212 |
+
--max_train_steps=800
|
| 213 |
+
```
|
| 214 |
+
</pt>
|
| 215 |
+
<jax>
|
| 216 |
+
```bash
|
| 217 |
+
export MODEL_NAME="duongna/stable-diffusion-v1-4-flax"
|
| 218 |
+
export INSTANCE_DIR="path-to-instance-images"
|
| 219 |
+
export CLASS_DIR="path-to-class-images"
|
| 220 |
+
export OUTPUT_DIR="path-to-save-model"
|
| 221 |
+
|
| 222 |
+
python train_dreambooth_flax.py \
|
| 223 |
+
--pretrained_model_name_or_path=$MODEL_NAME \
|
| 224 |
+
--train_text_encoder \
|
| 225 |
+
--instance_data_dir=$INSTANCE_DIR \
|
| 226 |
+
--class_data_dir=$CLASS_DIR \
|
| 227 |
+
--output_dir=$OUTPUT_DIR \
|
| 228 |
+
--with_prior_preservation --prior_loss_weight=1.0 \
|
| 229 |
+
--instance_prompt="a photo of sks dog" \
|
| 230 |
+
--class_prompt="a photo of dog" \
|
| 231 |
+
--resolution=512 \
|
| 232 |
+
--train_batch_size=1 \
|
| 233 |
+
--learning_rate=2e-6 \
|
| 234 |
+
--num_class_images=200 \
|
| 235 |
+
--max_train_steps=800
|
| 236 |
+
```
|
| 237 |
+
</jax>
|
| 238 |
+
</frameworkcontent>
|
| 239 |
+
|
| 240 |
+
## LoRA로 파인튜닝하기
|
| 241 |
+
|
| 242 |
+
DreamBooth에서 대규모 모델의 학습을 가속화하기 위한 파인튜닝 기술인 LoRA(Low-Rank Adaptation of Large Language Models)를 사용할 수 있습니다. 자세한 내용은 [LoRA 학습](training/lora#dreambooth) 가이드를 참조하세요.
|
| 243 |
+
|
| 244 |
+
### 학습 중 체크포인트 저장하기
|
| 245 |
+
|
| 246 |
+
Dreambooth로 훈련하는 동안 과적합하기 쉬우므로, 때때로 학습 중에 정기적인 체크포인트를 저장하는 것이 유용합니다. 중간 체크포인트 중 하나가 최종 모델보다 더 잘 작동할 수 있습니다! 체크포인트 저장 기능을 활성화하려면 학습 스크립트에 다음 인수를 전달해야 합니다:
|
| 247 |
+
|
| 248 |
+
```bash
|
| 249 |
+
--checkpointing_steps=500
|
| 250 |
+
```
|
| 251 |
+
|
| 252 |
+
이렇게 하면 `output_dir`의 하위 폴더에 전체 학습 상태가 저장됩니다. 하위 폴더 이름은 접두사 `checkpoint-`로 시작하고 지금까지 수행된 step 수입니다. 예시로 `checkpoint-1500`은 1500 학습 step 후에 저장된 체크포인트입니다.
|
| 253 |
+
|
| 254 |
+
#### 저장된 체크포인트에서 훈련 재개하기
|
| 255 |
+
|
| 256 |
+
저장된 체크포인트에서 훈련을 재개하려면, `--resume_from_checkpoint` 인수를 전달한 다음 사용할 체크포인트의 이름을 지정하면 됩니다. 특수 문자열 `"latest"`를 사용하여 저장된 마지막 체크포인트(즉, step 수가 가장 많은 체크포인트)에서 재개할 수도 있습니다. 예를 들어 다음은 1500 step 후에 저장된 체크포인트에서부터 학습을 재개합니다:
|
| 257 |
+
|
| 258 |
+
```bash
|
| 259 |
+
--resume_from_checkpoint="checkpoint-1500"
|
| 260 |
+
```
|
| 261 |
+
|
| 262 |
+
원하는 경우 일부 하이퍼파라미터를 조정할 수 있습니다.
|
| 263 |
+
|
| 264 |
+
#### 저장된 체크포인트를 사용하여 추론 수행하기
|
| 265 |
+
|
| 266 |
+
저장된 체크포인트는 훈련 재개에 적합한 형식으로 저장됩니다. 여기에는 모델 가중치뿐만 아니라 옵티마이저, 데이터 로더 및 학습률의 상태도 포함됩니다.
|
| 267 |
+
|
| 268 |
+
**`"accelerate>=0.16.0"`**이 설치된 경우 다음 코드를 사용하여 중간 체크포인트에서 추론을 실행합니다.
|
| 269 |
+
|
| 270 |
+
```python
|
| 271 |
+
from diffusers import DiffusionPipeline, UNet2DConditionModel
|
| 272 |
+
from transformers import CLIPTextModel
|
| 273 |
+
import torch
|
| 274 |
+
|
| 275 |
+
# 학습에 사용된 것과 동일한 인수(model, revision)로 파이프라인을 불러옵니다.
|
| 276 |
+
model_id = "CompVis/stable-diffusion-v1-4"
|
| 277 |
+
|
| 278 |
+
unet = UNet2DConditionModel.from_pretrained("/sddata/dreambooth/daruma-v2-1/checkpoint-100/unet")
|
| 279 |
+
|
| 280 |
+
# `args.train_text_encoder`로 학습한 경우면 텍스트 인코더를 꼭 불러오세요
|
| 281 |
+
text_encoder = CLIPTextModel.from_pretrained("/sddata/dreambooth/daruma-v2-1/checkpoint-100/text_encoder")
|
| 282 |
+
|
| 283 |
+
pipeline = DiffusionPipeline.from_pretrained(model_id, unet=unet, text_encoder=text_encoder, dtype=torch.float16)
|
| 284 |
+
pipeline.to("cuda")
|
| 285 |
+
|
| 286 |
+
# 추론을 수행하거나 저장하거나, 허브에 푸시합니다.
|
| 287 |
+
pipeline.save_pretrained("dreambooth-pipeline")
|
| 288 |
+
```
|
| 289 |
+
|
| 290 |
+
If you have **`"accelerate<0.16.0"`** installed, you need to convert it to an inference pipeline first:
|
| 291 |
+
|
| 292 |
+
```python
|
| 293 |
+
from accelerate import Accelerator
|
| 294 |
+
from diffusers import DiffusionPipeline
|
| 295 |
+
|
| 296 |
+
# 학습에 사용된 것과 동일한 인수(model, revision)로 파이프라인을 불러옵니다.
|
| 297 |
+
model_id = "CompVis/stable-diffusion-v1-4"
|
| 298 |
+
pipeline = DiffusionPipeline.from_pretrained(model_id)
|
| 299 |
+
|
| 300 |
+
accelerator = Accelerator()
|
| 301 |
+
|
| 302 |
+
# 초기 학습에 `--train_text_encoder`가 사용된 경우 text_encoder를 사용합니다.
|
| 303 |
+
unet, text_encoder = accelerator.prepare(pipeline.unet, pipeline.text_encoder)
|
| 304 |
+
|
| 305 |
+
# 체크포인트 경로로부터 상태를 복원합니다. 여기서는 절대 경로를 사용해야 합니다.
|
| 306 |
+
accelerator.load_state("/sddata/dreambooth/daruma-v2-1/checkpoint-100")
|
| 307 |
+
|
| 308 |
+
# unwrapped 모델로 파이프라인을 다시 빌드합니다.(.unet and .text_encoder로의 할당도 작동해야 합니다)
|
| 309 |
+
pipeline = DiffusionPipeline.from_pretrained(
|
| 310 |
+
model_id,
|
| 311 |
+
unet=accelerator.unwrap_model(unet),
|
| 312 |
+
text_encoder=accelerator.unwrap_model(text_encoder),
|
| 313 |
+
)
|
| 314 |
+
|
| 315 |
+
# 추론을 수행하거나 저장하거나, 허브에 푸시합니다.
|
| 316 |
+
pipeline.save_pretrained("dreambooth-pipeline")
|
| 317 |
+
```
|
| 318 |
+
|
| 319 |
+
## 각 GPU 용량에서의 최적화
|
| 320 |
+
|
| 321 |
+
하드웨어에 따라 16GB에서 8GB까지 GPU에서 DreamBooth를 최적화하는 몇 가지 방법이 있습니다!
|
| 322 |
+
|
| 323 |
+
### xFormers
|
| 324 |
+
|
| 325 |
+
[xFormers](https://github.com/facebookresearch/xformers)는 Transformers를 최적화하기 위한 toolbox이며, 🧨 Diffusers에서 사용되는[memory-efficient attention](https://facebookresearch.github.io/xformers/components/ops.html#module-xformers.ops) 메커니즘을 포함하고 있습니다. [xFormers를 설치](./optimization/xformers)한 다음 학습 스크립트에 다음 인수를 추가합니다:
|
| 326 |
+
|
| 327 |
+
```bash
|
| 328 |
+
--enable_xformers_memory_efficient_attention
|
| 329 |
+
```
|
| 330 |
+
|
| 331 |
+
xFormers는 Flax에서 사용할 수 없습니다.
|
| 332 |
+
|
| 333 |
+
### 그래디언트 없음으로 설정
|
| 334 |
+
|
| 335 |
+
메모리 사용량을 줄일 수 있는 또 다른 방법은 [기울기 설정](https://pytorch.org/docs/stable/generated/torch.optim.Optimizer.zero_grad.html)을 0 대신 `None`으로 하는 것입니다. 그러나 이로 인해 특정 동작이 변경될 수 있으므로 문제가 발생하면 이 인수를 제거해 보십시오. 학습 스크립트에 다음 인수를 추가하여 그래디언트를 `None`으로 설정합니다.
|
| 336 |
+
|
| 337 |
+
```bash
|
| 338 |
+
--set_grads_to_none
|
| 339 |
+
```
|
| 340 |
+
|
| 341 |
+
### 16GB GPU
|
| 342 |
+
|
| 343 |
+
Gradient checkpointing과 [bitsandbytes](https://github.com/TimDettmers/bitsandbytes)의 8비트 옵티마이저의 도움으로, 16GB GPU에서 dreambooth를 훈련할 수 있습니다. bitsandbytes가 설치되어 있는지 확인하세요:
|
| 344 |
+
|
| 345 |
+
```bash
|
| 346 |
+
pip install bitsandbytes
|
| 347 |
+
```
|
| 348 |
+
|
| 349 |
+
그 다음, 학습 스크립트에 `--use_8bit_adam` 옵션을 명시합니다:
|
| 350 |
+
|
| 351 |
+
```bash
|
| 352 |
+
export MODEL_NAME="CompVis/stable-diffusion-v1-4"
|
| 353 |
+
export INSTANCE_DIR="path_to_training_images"
|
| 354 |
+
export CLASS_DIR="path_to_class_images"
|
| 355 |
+
export OUTPUT_DIR="path_to_saved_model"
|
| 356 |
+
|
| 357 |
+
accelerate launch train_dreambooth.py \
|
| 358 |
+
--pretrained_model_name_or_path=$MODEL_NAME \
|
| 359 |
+
--instance_data_dir=$INSTANCE_DIR \
|
| 360 |
+
--class_data_dir=$CLASS_DIR \
|
| 361 |
+
--output_dir=$OUTPUT_DIR \
|
| 362 |
+
--with_prior_preservation --prior_loss_weight=1.0 \
|
| 363 |
+
--instance_prompt="a photo of sks dog" \
|
| 364 |
+
--class_prompt="a photo of dog" \
|
| 365 |
+
--resolution=512 \
|
| 366 |
+
--train_batch_size=1 \
|
| 367 |
+
--gradient_accumulation_steps=2 --gradient_checkpointing \
|
| 368 |
+
--use_8bit_adam \
|
| 369 |
+
--learning_rate=5e-6 \
|
| 370 |
+
--lr_scheduler="constant" \
|
| 371 |
+
--lr_warmup_steps=0 \
|
| 372 |
+
--num_class_images=200 \
|
| 373 |
+
--max_train_steps=800
|
| 374 |
+
```
|
| 375 |
+
|
| 376 |
+
### 12GB GPU
|
| 377 |
+
|
| 378 |
+
12GB GPU에서 DreamBooth를 실행하려면 gradient checkpointing, 8비트 옵티마이저, xFormers를 활성화하고 그래디언트를 `None`으로 설정해야 합니다.
|
| 379 |
+
|
| 380 |
+
```bash
|
| 381 |
+
export MODEL_NAME="CompVis/stable-diffusion-v1-4"
|
| 382 |
+
export INSTANCE_DIR="path-to-instance-images"
|
| 383 |
+
export CLASS_DIR="path-to-class-images"
|
| 384 |
+
export OUTPUT_DIR="path-to-save-model"
|
| 385 |
+
|
| 386 |
+
accelerate launch train_dreambooth.py \
|
| 387 |
+
--pretrained_model_name_or_path=$MODEL_NAME \
|
| 388 |
+
--instance_data_dir=$INSTANCE_DIR \
|
| 389 |
+
--class_data_dir=$CLASS_DIR \
|
| 390 |
+
--output_dir=$OUTPUT_DIR \
|
| 391 |
+
--with_prior_preservation --prior_loss_weight=1.0 \
|
| 392 |
+
--instance_prompt="a photo of sks dog" \
|
| 393 |
+
--class_prompt="a photo of dog" \
|
| 394 |
+
--resolution=512 \
|
| 395 |
+
--train_batch_size=1 \
|
| 396 |
+
--gradient_accumulation_steps=1 --gradient_checkpointing \
|
| 397 |
+
--use_8bit_adam \
|
| 398 |
+
--enable_xformers_memory_efficient_attention \
|
| 399 |
+
--set_grads_to_none \
|
| 400 |
+
--learning_rate=2e-6 \
|
| 401 |
+
--lr_scheduler="constant" \
|
| 402 |
+
--lr_warmup_steps=0 \
|
| 403 |
+
--num_class_images=200 \
|
| 404 |
+
--max_train_steps=800
|
| 405 |
+
```
|
| 406 |
+
|
| 407 |
+
### 8GB GPU에서 학습하기
|
| 408 |
+
|
| 409 |
+
8GB GPU에 대해서는 [DeepSpeed](https://www.deepspeed.ai/)를 사용해 일부 텐서를 VRAM에서 CPU 또는 NVME로 오프로드하여 더 적은 GPU 메모리로 학습할 수도 있습니다.
|
| 410 |
+
|
| 411 |
+
🤗 Accelerate 환경을 구성하려면 다음 명령을 실행하세요:
|
| 412 |
+
|
| 413 |
+
```bash
|
| 414 |
+
accelerate config
|
| 415 |
+
```
|
| 416 |
+
|
| 417 |
+
환경 구성 중에 DeepSpeed를 사용할 것을 확인하세요.
|
| 418 |
+
그러면 DeepSpeed stage 2, fp16 혼합 정밀도를 결합하고 모델 매개변수와 옵티마이저 상태를 모두 CPU로 오프로드하면 8GB VRAM 미만에서 학습할 수 있습니다.
|
| 419 |
+
단점은 더 많은 시스템 RAM(약 25GB)이 필요하다는 것입니다. 추가 구성 옵션은 [DeepSpeed 문서](https://huggingface.co/docs/accelerate/usage_guides/deepspeed)를 참조하세요.
|
| 420 |
+
|
| 421 |
+
또한 기본 Adam 옵티마이저를 DeepSpeed의 최적화된 Adam 버전으로 변경해야 합니다.
|
| 422 |
+
이는 상당한 속도 향상을 위한 Adam인 [`deepspeed.ops.adam.DeepSpeedCPUAdam`](https://deepspeed.readthedocs.io/en/latest/optimizers.html#adam-cpu)입니다.
|
| 423 |
+
`DeepSpeedCPUAdam`을 활성화하려면 시스템의 CUDA toolchain 버전이 PyTorch와 함께 설치된 것과 동일해야 합니다.
|
| 424 |
+
|
| 425 |
+
8비트 옵티마이저는 현재 DeepSpeed와 호환되지 않는 것 같습니다.
|
| 426 |
+
|
| 427 |
+
다음 명령으로 학습을 시작합니다:
|
| 428 |
+
|
| 429 |
+
```bash
|
| 430 |
+
export MODEL_NAME="CompVis/stable-diffusion-v1-4"
|
| 431 |
+
export INSTANCE_DIR="path_to_training_images"
|
| 432 |
+
export CLASS_DIR="path_to_class_images"
|
| 433 |
+
export OUTPUT_DIR="path_to_saved_model"
|
| 434 |
+
|
| 435 |
+
accelerate launch train_dreambooth.py \
|
| 436 |
+
--pretrained_model_name_or_path=$MODEL_NAME \
|
| 437 |
+
--instance_data_dir=$INSTANCE_DIR \
|
| 438 |
+
--class_data_dir=$CLASS_DIR \
|
| 439 |
+
--output_dir=$OUTPUT_DIR \
|
| 440 |
+
--with_prior_preservation --prior_loss_weight=1.0 \
|
| 441 |
+
--instance_prompt="a photo of sks dog" \
|
| 442 |
+
--class_prompt="a photo of dog" \
|
| 443 |
+
--resolution=512 \
|
| 444 |
+
--train_batch_size=1 \
|
| 445 |
+
--sample_batch_size=1 \
|
| 446 |
+
--gradient_accumulation_steps=1 --gradient_checkpointing \
|
| 447 |
+
--learning_rate=5e-6 \
|
| 448 |
+
--lr_scheduler="constant" \
|
| 449 |
+
--lr_warmup_steps=0 \
|
| 450 |
+
--num_class_images=200 \
|
| 451 |
+
--max_train_steps=800 \
|
| 452 |
+
--mixed_precision=fp16
|
| 453 |
+
```
|
| 454 |
+
|
| 455 |
+
## 추론
|
| 456 |
+
|
| 457 |
+
모델을 학습한 후에는, 모델이 저장된 경로를 지정해 [`StableDiffusionPipeline`]로 추론을 수행할 수 있습니다. 프롬프트에 학습에 사용된 특수 `식별자`(이전 예시의 `sks`)가 포함되어 있는지 확인하세요.
|
| 458 |
+
|
| 459 |
+
**`"accelerate>=0.16.0"`**이 설치되어 있는 경우 다음 코드를 사용하여 중간 체크포인트에서 추론을 실행할 수 있습니다:
|
| 460 |
+
|
| 461 |
+
```python
|
| 462 |
+
from diffusers import StableDiffusionPipeline
|
| 463 |
+
import torch
|
| 464 |
+
|
| 465 |
+
model_id = "path_to_saved_model"
|
| 466 |
+
pipe = StableDiffusionPipeline.from_pretrained(model_id, torch_dtype=torch.float16).to("cuda")
|
| 467 |
+
|
| 468 |
+
prompt = "A photo of sks dog in a bucket"
|
| 469 |
+
image = pipe(prompt, num_inference_steps=50, guidance_scale=7.5).images[0]
|
| 470 |
+
|
| 471 |
+
image.save("dog-bucket.png")
|
| 472 |
+
```
|
| 473 |
+
|
| 474 |
+
[저장된 학습 체크포인트](#inference-from-a-saved-checkpoint)에서도 추론을 실행할 수도 있습니다.
|
tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/training/instructpix2pix.md
ADDED
|
@@ -0,0 +1,211 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2024 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# InstructPix2Pix
|
| 14 |
+
|
| 15 |
+
[InstructPix2Pix](https://huggingface.co/papers/2211.09800)는 text-conditioned diffusion 모델이 한 이미지에 편집을 따를 수 있도록 파인튜닝하는 방법입니다. 이 방법을 사용하여 파인튜닝된 모델은 다음을 입력으로 사용합니다:
|
| 16 |
+
|
| 17 |
+
<p align="center">
|
| 18 |
+
<img src="https://huggingface.co/datasets/diffusers/docs-images/resolve/main/evaluation_diffusion_models/edit-instruction.png" alt="instructpix2pix-inputs" width=600/>
|
| 19 |
+
</p>
|
| 20 |
+
|
| 21 |
+
출력은 입력 이미지에 편집 지시가 반영된 "수정된" 이미지입니다:
|
| 22 |
+
|
| 23 |
+
<p align="center">
|
| 24 |
+
<img src="https://huggingface.co/datasets/diffusers/docs-images/resolve/main/output-gs%407-igs%401-steps%4050.png" alt="instructpix2pix-output" width=600/>
|
| 25 |
+
</p>
|
| 26 |
+
|
| 27 |
+
`train_instruct_pix2pix.py` 스크립트([여기](https://github.com/huggingface/diffusers/blob/main/examples/instruct_pix2pix/train_instruct_pix2pix.py)에서 찾을 수 있습니다.)는 학습 절차를 설명하고 Stable Diffusion에 적용할 수 있는 방법을 보여줍니다.
|
| 28 |
+
|
| 29 |
+
|
| 30 |
+
*** `train_instruct_pix2pix.py`는 [원래 구현](https://github.com/timothybrooks/instruct-pix2pix)에 충실하면서 InstructPix2Pix 학습 절차를 구현하고 있지만, [소규모 데이터셋](https://huggingface.co/datasets/fusing/instructpix2pix-1000-samples)에서만 테스트를 했습니다. 이는 최종 결과에 영향을 끼칠 수 있습니다. 더 나은 결과를 위해, 더 큰 데이터셋에서 더 길게 학습하는 것을 권장합니다. [여기](https://huggingface.co/datasets/timbrooks/instructpix2pix-clip-filtered)에서 InstructPix2Pix 학습을 위해 큰 데이터셋을 찾을 수 있습니다.
|
| 31 |
+
***
|
| 32 |
+
|
| 33 |
+
## PyTorch로 로컬에서 실행하기
|
| 34 |
+
|
| 35 |
+
### 종속성(dependencies) 설치하기
|
| 36 |
+
|
| 37 |
+
이 스크립트를 실행하기 전에, 라이브러리의 학습 종속성을 설치하세요:
|
| 38 |
+
|
| 39 |
+
**중요**
|
| 40 |
+
|
| 41 |
+
최신 버전의 예제 스크립트를 성공적으로 실행하기 위해, **원본으로부터 설치**하는 것과 예제 스크립트를 자주 업데이트하고 예제별 요구사항을 설치하기 때문에 최신 상태로 유지하는 것을 권장합니다. 이를 위해, 새로운 가상 환경에서 다음 스텝을 실행하세요:
|
| 42 |
+
|
| 43 |
+
```bash
|
| 44 |
+
git clone https://github.com/huggingface/diffusers
|
| 45 |
+
cd diffusers
|
| 46 |
+
pip install -e .
|
| 47 |
+
```
|
| 48 |
+
|
| 49 |
+
cd 명령어로 예제 폴더로 이동하세요.
|
| 50 |
+
```bash
|
| 51 |
+
cd examples/instruct_pix2pix
|
| 52 |
+
```
|
| 53 |
+
|
| 54 |
+
이제 실행하세요.
|
| 55 |
+
```bash
|
| 56 |
+
pip install -r requirements.txt
|
| 57 |
+
```
|
| 58 |
+
|
| 59 |
+
그리고 [🤗Accelerate](https://github.com/huggingface/accelerate/) 환경에서 초기화하세요:
|
| 60 |
+
|
| 61 |
+
```bash
|
| 62 |
+
accelerate config
|
| 63 |
+
```
|
| 64 |
+
|
| 65 |
+
혹은 환경에 대한 질문 없이 기본적인 accelerate 구성을 사용하려면 다음을 실행하세요.
|
| 66 |
+
|
| 67 |
+
```bash
|
| 68 |
+
accelerate config default
|
| 69 |
+
```
|
| 70 |
+
|
| 71 |
+
혹은 사용 중인 환경이 notebook과 같은 대화형 쉘은 지원하지 않는 경우는 다음 절차를 따라주세요.
|
| 72 |
+
|
| 73 |
+
```python
|
| 74 |
+
from accelerate.utils import write_basic_config
|
| 75 |
+
|
| 76 |
+
write_basic_config()
|
| 77 |
+
```
|
| 78 |
+
|
| 79 |
+
### 예시
|
| 80 |
+
|
| 81 |
+
이전에 언급했듯이, 학습을 위해 [작은 데이터셋](https://huggingface.co/datasets/fusing/instructpix2pix-1000-samples)을 사용할 것입니다. 그 데이터셋은 InstructPix2Pix 논문에서 사용된 [원래의 데이터셋](https://huggingface.co/datasets/timbrooks/instructpix2pix-clip-filtered)보다 작은 버전입니다. 자신의 데이터셋을 사용하기 위해, [학습을 위한 데이터셋 만들기](create_dataset) 가이드를 참고하세요.
|
| 82 |
+
|
| 83 |
+
`MODEL_NAME` 환경 변수(허브 모델 레포지토리 또는 모델 가중치가 포함된 폴더 경로)를 지정하고 [`pretrained_model_name_or_path`](https://huggingface.co/docs/diffusers/en/api/diffusion_pipeline#diffusers.DiffusionPipeline.from_pretrained.pretrained_model_name_or_path) 인수에 전달합니다. `DATASET_ID`에 데이터셋 이름을 지정해야 합니다:
|
| 84 |
+
|
| 85 |
+
|
| 86 |
+
```bash
|
| 87 |
+
export MODEL_NAME="stable-diffusion-v1-5/stable-diffusion-v1-5"
|
| 88 |
+
export DATASET_ID="fusing/instructpix2pix-1000-samples"
|
| 89 |
+
```
|
| 90 |
+
|
| 91 |
+
지금, 학습을 실행할 수 있습니다. 스크립트는 레포지토리의 하위 폴더의 모든 구성요소(`feature_extractor`, `scheduler`, `text_encoder`, `unet` 등)를 저장합니다.
|
| 92 |
+
|
| 93 |
+
```bash
|
| 94 |
+
accelerate launch --mixed_precision="fp16" train_instruct_pix2pix.py \
|
| 95 |
+
--pretrained_model_name_or_path=$MODEL_NAME \
|
| 96 |
+
--dataset_name=$DATASET_ID \
|
| 97 |
+
--enable_xformers_memory_efficient_attention \
|
| 98 |
+
--resolution=256 --random_flip \
|
| 99 |
+
--train_batch_size=4 --gradient_accumulation_steps=4 --gradient_checkpointing \
|
| 100 |
+
--max_train_steps=15000 \
|
| 101 |
+
--checkpointing_steps=5000 --checkpoints_total_limit=1 \
|
| 102 |
+
--learning_rate=5e-05 --max_grad_norm=1 --lr_warmup_steps=0 \
|
| 103 |
+
--conditioning_dropout_prob=0.05 \
|
| 104 |
+
--mixed_precision=fp16 \
|
| 105 |
+
--seed=42 \
|
| 106 |
+
--push_to_hub
|
| 107 |
+
```
|
| 108 |
+
|
| 109 |
+
|
| 110 |
+
추가적으로, 가중치와 바이어스를 학습 과정에 모니터링하여 검증 추론을 수행하는 것을 지원합니다. `report_to="wandb"`와 이 기능을 사용할 수 있습니다:
|
| 111 |
+
|
| 112 |
+
```bash
|
| 113 |
+
accelerate launch --mixed_precision="fp16" train_instruct_pix2pix.py \
|
| 114 |
+
--pretrained_model_name_or_path=$MODEL_NAME \
|
| 115 |
+
--dataset_name=$DATASET_ID \
|
| 116 |
+
--enable_xformers_memory_efficient_attention \
|
| 117 |
+
--resolution=256 --random_flip \
|
| 118 |
+
--train_batch_size=4 --gradient_accumulation_steps=4 --gradient_checkpointing \
|
| 119 |
+
--max_train_steps=15000 \
|
| 120 |
+
--checkpointing_steps=5000 --checkpoints_total_limit=1 \
|
| 121 |
+
--learning_rate=5e-05 --max_grad_norm=1 --lr_warmup_steps=0 \
|
| 122 |
+
--conditioning_dropout_prob=0.05 \
|
| 123 |
+
--mixed_precision=fp16 \
|
| 124 |
+
--val_image_url="https://hf.co/datasets/diffusers/diffusers-images-docs/resolve/main/mountain.png" \
|
| 125 |
+
--validation_prompt="make the mountains snowy" \
|
| 126 |
+
--seed=42 \
|
| 127 |
+
--report_to=wandb \
|
| 128 |
+
--push_to_hub
|
| 129 |
+
```
|
| 130 |
+
|
| 131 |
+
모델 디버깅에 유용한 이 평가 방법 권장합니다. 이를 사용하기 위해 `wandb`를 설치하는 것을 주목해주세요. `pip install wandb`로 실행해 `wandb`를 설치할 수 있습니다.
|
| 132 |
+
|
| 133 |
+
[여기](https://wandb.ai/sayakpaul/instruct-pix2pix/runs/ctr3kovq), 몇 가지 평가 방법과 학습 파라미터를 포함하는 예시를 볼 수 있습니다.
|
| 134 |
+
|
| 135 |
+
***참고: 원본 논문에서, 저자들은 256x256 이미지 해상도로 학습한 모델로 512x512와 같은 더 큰 해상도로 잘 일반화되는 것을 볼 수 있었습니다. 이는 학습에 사용한 큰 데이터셋을 사용했기 때문입니다.***
|
| 136 |
+
|
| 137 |
+
## 다수의 GPU로 학습하기
|
| 138 |
+
|
| 139 |
+
`accelerate`는 원활한 다수의 GPU로 학습을 가능하게 합니다. `accelerate`로 분산 학습을 실행하는 [여기](https://huggingface.co/docs/accelerate/basic_tutorials/launch) 설명을 따라 해 주시기 바랍니다. 예시의 명령어 입니다:
|
| 140 |
+
|
| 141 |
+
|
| 142 |
+
```bash
|
| 143 |
+
accelerate launch --mixed_precision="fp16" --multi_gpu train_instruct_pix2pix.py \
|
| 144 |
+
--pretrained_model_name_or_path=stable-diffusion-v1-5/stable-diffusion-v1-5 \
|
| 145 |
+
--dataset_name=sayakpaul/instructpix2pix-1000-samples \
|
| 146 |
+
--use_ema \
|
| 147 |
+
--enable_xformers_memory_efficient_attention \
|
| 148 |
+
--resolution=512 --random_flip \
|
| 149 |
+
--train_batch_size=4 --gradient_accumulation_steps=4 --gradient_checkpointing \
|
| 150 |
+
--max_train_steps=15000 \
|
| 151 |
+
--checkpointing_steps=5000 --checkpoints_total_limit=1 \
|
| 152 |
+
--learning_rate=5e-05 --lr_warmup_steps=0 \
|
| 153 |
+
--conditioning_dropout_prob=0.05 \
|
| 154 |
+
--mixed_precision=fp16 \
|
| 155 |
+
--seed=42 \
|
| 156 |
+
--push_to_hub
|
| 157 |
+
```
|
| 158 |
+
|
| 159 |
+
## 추론하기
|
| 160 |
+
|
| 161 |
+
일단 학습이 완료되면, 추론 할 수 있습니다:
|
| 162 |
+
|
| 163 |
+
```python
|
| 164 |
+
import PIL
|
| 165 |
+
import requests
|
| 166 |
+
import torch
|
| 167 |
+
from diffusers import StableDiffusionInstructPix2PixPipeline
|
| 168 |
+
|
| 169 |
+
model_id = "your_model_id" # <- 이를 수정하세요.
|
| 170 |
+
pipe = StableDiffusionInstructPix2PixPipeline.from_pretrained(model_id, torch_dtype=torch.float16).to("cuda")
|
| 171 |
+
generator = torch.Generator("cuda").manual_seed(0)
|
| 172 |
+
|
| 173 |
+
url = "https://huggingface.co/datasets/sayakpaul/sample-datasets/resolve/main/test_pix2pix_4.png"
|
| 174 |
+
|
| 175 |
+
|
| 176 |
+
def download_image(url):
|
| 177 |
+
image = PIL.Image.open(requests.get(url, stream=True).raw)
|
| 178 |
+
image = PIL.ImageOps.exif_transpose(image)
|
| 179 |
+
image = image.convert("RGB")
|
| 180 |
+
return image
|
| 181 |
+
|
| 182 |
+
|
| 183 |
+
image = download_image(url)
|
| 184 |
+
prompt = "wipe out the lake"
|
| 185 |
+
num_inference_steps = 20
|
| 186 |
+
image_guidance_scale = 1.5
|
| 187 |
+
guidance_scale = 10
|
| 188 |
+
|
| 189 |
+
edited_image = pipe(
|
| 190 |
+
prompt,
|
| 191 |
+
image=image,
|
| 192 |
+
num_inference_steps=num_inference_steps,
|
| 193 |
+
image_guidance_scale=image_guidance_scale,
|
| 194 |
+
guidance_scale=guidance_scale,
|
| 195 |
+
generator=generator,
|
| 196 |
+
).images[0]
|
| 197 |
+
edited_image.save("edited_image.png")
|
| 198 |
+
```
|
| 199 |
+
|
| 200 |
+
학습 스크립트를 사용해 얻은 예시의 모델 레포지토리는 여기 [sayakpaul/instruct-pix2pix](https://huggingface.co/sayakpaul/instruct-pix2pix)에서 확인할 수 있습니다.
|
| 201 |
+
|
| 202 |
+
성능을 위한 속도와 품질을 제어하기 위해 세 가지 파라미터를 사용하는 것이 좋습니다:
|
| 203 |
+
|
| 204 |
+
* `num_inference_steps`
|
| 205 |
+
* `image_guidance_scale`
|
| 206 |
+
* `guidance_scale`
|
| 207 |
+
|
| 208 |
+
특히, `image_guidance_scale`와 `guidance_scale`는 생성된("수정된") 이미지에서 큰 영향을 미칠 수 있습니다.([여기](https://twitter.com/RisingSayak/status/1628392199196151808?s=20)예시를 참고해주세요.)
|
| 209 |
+
|
| 210 |
+
|
| 211 |
+
만약 InstructPix2Pix 학습 방법을 사용해 몇 가지 흥미로운 방법을 찾고 있다면, 이 블로그 게시물[Instruction-tuning Stable Diffusion with InstructPix2Pix](https://huggingface.co/blog/instruction-tuning-sd)을 확인해주세요.
|
tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/training/lora.md
ADDED
|
@@ -0,0 +1,128 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2024 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Low-Rank Adaptation of Large Language Models (LoRA)
|
| 14 |
+
|
| 15 |
+
[[open-in-colab]]
|
| 16 |
+
|
| 17 |
+
<Tip warning={true}>
|
| 18 |
+
|
| 19 |
+
현재 LoRA는 [`UNet2DConditionalModel`]의 어텐션 레이어에서만 지원됩니다.
|
| 20 |
+
|
| 21 |
+
</Tip>
|
| 22 |
+
|
| 23 |
+
[LoRA(Low-Rank Adaptation of Large Language Models)](https://huggingface.co/papers/2106.09685)는 메모리를 적게 사용하면서 대규모 모델의 학습을 가속화하는 학습 방법입니다. 이는 rank-decomposition weight 행렬 쌍(**업데이트 행렬**이라고 함)을 추가하고 새로 추가된 가중치**만** 학습합니다. 여기에는 몇 가지 장점이 있습니다.
|
| 24 |
+
|
| 25 |
+
- 이전에 미리 학습된 가중치는 고정된 상태로 유지되므로 모델이 [치명적인 망각](https://www.pnas.org/doi/10.1073/pnas.1611835114) 경향이 없습니다.
|
| 26 |
+
- Rank-decomposition 행렬은 원래 모델보다 파라메터 수가 훨씬 적으므로 학습된 LoRA 가중치를 쉽게 끼워넣을 수 있습니다.
|
| 27 |
+
- LoRA 매트릭스는 일반적으로 원본 모델의 어텐션 레이어에 추가됩니다. 🧨 Diffusers는 [`~diffusers.loaders.UNet2DConditionLoadersMixin.load_attn_procs`] 메서드를 제공하여 LoRA 가중치를 모델의 어텐션 레이어로 불러옵니다. `scale` 매개변수를 통해 모델이 새로운 학습 이미지에 맞게 조정되는 범위를 제어할 수 있습니다.
|
| 28 |
+
- 메모리 효율성이 향상되어 Tesla T4, RTX 3080 또는 RTX 2080 Ti와 같은 소비자용 GPU에서 파인튜닝을 실행할 수 있습니다! T4와 같은 GPU는 무료이며 Kaggle 또는 Google Colab 노트북에서 쉽게 액세스할 수 있습니다.
|
| 29 |
+
|
| 30 |
+
|
| 31 |
+
<Tip>
|
| 32 |
+
|
| 33 |
+
💡 LoRA는 어텐션 레이어에만 한정되지는 않습니다. 저자는 언어 모델의 어텐션 레이어를 수정하는 것이 매우 효율적으로 죻은 성능을 얻기에 충분하다는 것을 발견했습니다. 이것이 LoRA 가중치를 모델의 어텐션 레이어에 추가하는 것이 일반적인 이유입니다. LoRA 작동 방식에 대한 자세한 내용은 [Using LoRA for effective Stable Diffusion fine-tuning](https://huggingface.co/blog/lora) 블로그를 확인하세요!
|
| 34 |
+
|
| 35 |
+
</Tip>
|
| 36 |
+
|
| 37 |
+
[cloneofsimo](https://github.com/cloneofsimo)는 인기 있는 [lora](https://github.com/cloneofsimo/lora) GitHub 리포지토리에서 Stable Diffusion을 위한 LoRA 학습을 최초로 시도했습니다. 🧨 Diffusers는 [text-to-image 생성](https://github.com/huggingface/diffusers/tree/main/examples/text_to_image#training-with-lora) 및 [DreamBooth](https://github.com/huggingface/diffusers/tree/main/examples/dreambooth#training-with-low-rank-adaptation-of-large-language-models-lora)을 지원합니다. 이 가이드는 두 가지를 모두 수행하는 방법을 보여줍니다.
|
| 38 |
+
|
| 39 |
+
모델을 저장하거나 커뮤니티와 공유하려면 Hugging Face 계정에 로그인하세요(아직 계정이 없는 경우 [생성](https://huggingface.co/join)하세요):
|
| 40 |
+
|
| 41 |
+
```bash
|
| 42 |
+
huggingface-cli login
|
| 43 |
+
```
|
| 44 |
+
|
| 45 |
+
## Text-to-image
|
| 46 |
+
|
| 47 |
+
수십억 개의 파라메터들이 있는 Stable Diffusion과 같은 모델을 파인튜닝하는 것은 느리고 어려울 수 있습니다. LoRA를 사용하면 diffusion 모델을 파인튜닝하는 것이 훨씬 쉽고 빠릅니다. 8비트 옵티마이저와 같은 트릭에 의존하지 않고도 11GB의 GPU RAM으로 하드웨어에서 실행할 수 있습니다.
|
| 48 |
+
|
| 49 |
+
|
| 50 |
+
### 학습[[dreambooth-training]]
|
| 51 |
+
|
| 52 |
+
[Naruto BLIP 캡션](https://huggingface.co/datasets/lambdalabs/naruto-blip-captions) 데이터셋으로 [`stable-diffusion-v1-5`](https://huggingface.co/stable-diffusion-v1-5/stable-diffusion-v1-5)를 파인튜닝해 나만의 포켓몬을 생성해 보겠습니다.
|
| 53 |
+
|
| 54 |
+
시작하려면 `MODEL_NAME` 및 `DATASET_NAME` 환경 변수가 설정되어 있는지 확인하십시오. `OUTPUT_DIR` 및 `HUB_MODEL_ID` 변수는 선택 사항이며 허브에서 모델을 저장할 위치를 지정합니다.
|
| 55 |
+
|
| 56 |
+
```bash
|
| 57 |
+
export MODEL_NAME="stable-diffusion-v1-5/stable-diffusion-v1-5"
|
| 58 |
+
export OUTPUT_DIR="/sddata/finetune/lora/naruto"
|
| 59 |
+
export HUB_MODEL_ID="naruto-lora"
|
| 60 |
+
export DATASET_NAME="lambdalabs/naruto-blip-captions"
|
| 61 |
+
```
|
| 62 |
+
|
| 63 |
+
학습을 시작하기 전에 알아야 할 몇 가지 플래그가 있습니다.
|
| 64 |
+
|
| 65 |
+
* `--push_to_hub`를 명시하면 학습된 LoRA 임베딩을 허브에 저장합니다.
|
| 66 |
+
* `--report_to=wandb`는 학습 결과를 가중치 및 편향 대시보드에 보고하고 기록합니다(예를 들어, 이 [보고서](https://wandb.ai/pcuenq/text2image-fine-tune/run/b4k1w0tn?workspace=user-pcuenq)를 참조하세요).
|
| 67 |
+
* `--learning_rate=1e-04`, 일반적으로 LoRA에서 사용하는 것보다 더 높은 학습률을 사용할 수 있습니다.
|
| 68 |
+
|
| 69 |
+
이제 학습을 시작할 준비가 되었습니다 (전체 학습 스크립트는 [여기](https://github.com/huggingface/diffusers/blob/main/examples/text_to_image/train_text_to_image_lora.py)에서 찾을 수 있습니다).
|
| 70 |
+
|
| 71 |
+
```bash
|
| 72 |
+
accelerate launch train_dreambooth_lora.py \
|
| 73 |
+
--pretrained_model_name_or_path=$MODEL_NAME \
|
| 74 |
+
--instance_data_dir=$INSTANCE_DIR \
|
| 75 |
+
--output_dir=$OUTPUT_DIR \
|
| 76 |
+
--instance_prompt="a photo of sks dog" \
|
| 77 |
+
--resolution=512 \
|
| 78 |
+
--train_batch_size=1 \
|
| 79 |
+
--gradient_accumulation_steps=1 \
|
| 80 |
+
--checkpointing_steps=100 \
|
| 81 |
+
--learning_rate=1e-4 \
|
| 82 |
+
--report_to="wandb" \
|
| 83 |
+
--lr_scheduler="constant" \
|
| 84 |
+
--lr_warmup_steps=0 \
|
| 85 |
+
--max_train_steps=500 \
|
| 86 |
+
--validation_prompt="A photo of sks dog in a bucket" \
|
| 87 |
+
--validation_epochs=50 \
|
| 88 |
+
--seed="0" \
|
| 89 |
+
--push_to_hub
|
| 90 |
+
```
|
| 91 |
+
|
| 92 |
+
### 추론[[dreambooth-inference]]
|
| 93 |
+
|
| 94 |
+
이제 [`StableDiffusionPipeline`]에서 기본 모델을 불러와 추론을 위해 모델을 사용할 수 있습니다:
|
| 95 |
+
|
| 96 |
+
```py
|
| 97 |
+
>>> import torch
|
| 98 |
+
>>> from diffusers import StableDiffusionPipeline
|
| 99 |
+
|
| 100 |
+
>>> model_base = "stable-diffusion-v1-5/stable-diffusion-v1-5"
|
| 101 |
+
|
| 102 |
+
>>> pipe = StableDiffusionPipeline.from_pretrained(model_base, torch_dtype=torch.float16)
|
| 103 |
+
```
|
| 104 |
+
|
| 105 |
+
*기본 모델의 가중치 위에* 파인튜닝된 DreamBooth 모델에서 LoRA 가중치를 불러온 다음, 더 빠른 추론을 위해 파이프라인을 GPU로 이동합니다. LoRA 가중치를 프리징된 사전 훈련된 모델 가중치와 병합할 때, 선택적으로 'scale' 매개변수로 어느 정도의 가중치를 병합할 지 조절할 수 있습니다:
|
| 106 |
+
|
| 107 |
+
<Tip>
|
| 108 |
+
|
| 109 |
+
💡 `0`의 `scale` 값은 LoRA 가중치를 사용하지 않아 원래 모델의 가중치만 사용한 것과 같고, `1`의 `scale` 값은 파인튜닝된 LoRA 가중치만 사용함을 의미합니다. 0과 1 사이의 값들은 두 결과들 사이로 보간됩니다.
|
| 110 |
+
|
| 111 |
+
</Tip>
|
| 112 |
+
|
| 113 |
+
```py
|
| 114 |
+
>>> pipe.unet.load_attn_procs(model_path)
|
| 115 |
+
>>> pipe.to("cuda")
|
| 116 |
+
# LoRA 파인튜닝된 모델의 가중치 절반과 기본 모델의 가중치 절반 사용
|
| 117 |
+
|
| 118 |
+
>>> image = pipe(
|
| 119 |
+
... "A picture of a sks dog in a bucket.",
|
| 120 |
+
... num_inference_steps=25,
|
| 121 |
+
... guidance_scale=7.5,
|
| 122 |
+
... cross_attention_kwargs={"scale": 0.5},
|
| 123 |
+
... ).images[0]
|
| 124 |
+
# 완전히 파인튜닝된 LoRA 모델의 가중치 사용
|
| 125 |
+
|
| 126 |
+
>>> image = pipe("A picture of a sks dog in a bucket.", num_inference_steps=25, guidance_scale=7.5).images[0]
|
| 127 |
+
>>> image.save("bucket-dog.png")
|
| 128 |
+
```
|
tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/training/overview.md
ADDED
|
@@ -0,0 +1,73 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2024 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# 🧨 Diffusers 학습 예시
|
| 14 |
+
|
| 15 |
+
이번 챕터에서는 다양한 유즈케이스들에 대한 예제 코드들을 통해 어떻게하면 효과적으로 `diffusers` 라이브러리를 사용할 수 있을까에 대해 알아보도록 하겠습니다.
|
| 16 |
+
|
| 17 |
+
**Note**: 혹시 오피셜한 예시코드를 찾고 있다면, [여기](https://github.com/huggingface/diffusers/tree/main/src/diffusers/pipelines)를 참고해보세요!
|
| 18 |
+
|
| 19 |
+
여기서 다룰 예시들은 다음을 지향합니다.
|
| 20 |
+
|
| 21 |
+
- **손쉬운 디펜던시 설치** (Self-contained) : 여기서 사용될 예시 코드들의 디펜던시 패키지들은 전부 `pip install` 명령어를 통해 설치 가능한 패키지들입니다. 또한 친절하게 `requirements.txt` 파일에 해당 패키지들이 명시되어 있어, `pip install -r requirements.txt`로 간편하게 해당 디펜던시들을 설치할 수 있습니다. 예시: [train_unconditional.py](https://github.com/huggingface/diffusers/blob/main/examples/unconditional_image_generation/train_unconditional.py), [requirements.txt](https://github.com/huggingface/diffusers/blob/main/examples/unconditional_image_generation/requirements.txt)
|
| 22 |
+
- **손쉬운 수정** (Easy-to-tweak) : 저희는 가능하면 많은 유즈 케이스들을 제공하고자 합니다. 하지만 예시는 결국 그저 예시라는 점들 기억해주세요. 여기서 제공되는 예시코드들을 그저 단순히 복사-붙혀넣기하는 식으로는 여러분이 마주한 문제들을 손쉽게 해결할 순 없을 것입니다. 다시 말해 어느 정도는 여러분의 상황과 니즈에 맞춰 코드를 일정 부분 고쳐나가야 할 것입니다. 따라서 대부분의 학습 예시들은 데이터의 전처리 과정과 학습 과정에 대한 코드들을 함께 제공함으로써, 사용자가 니즈에 맞게 손쉬운 수정할 수 있도록 돕고 있습니다.
|
| 23 |
+
- **입문자 친화적인** (Beginner-friendly) : 이번 챕터는 diffusion 모델과 `diffusers` 라이브러리에 대한 전반적인 이해를 돕기 위해 작성되었습니다. 따라서 diffusion 모델에 대한 최신 SOTA (state-of-the-art) 방법론들 가운데서도, 입문자에게는 많이 어려울 수 있다고 판단되면, 해당 방법론들은 여기서 다루지 않으려고 합니다.
|
| 24 |
+
- **하나의 태스크만 포함할 것**(One-purpose-only): 여기서 다룰 예시들은 하나의 태스크만 포함하고 있어야 합니다. 물론 이미지 초해상화(super-resolution)와 이미지 보정(modification)과 같은 유사한 모델링 프로세스를 갖는 태스크들이 존재하겠지만, 하나의 예제에 하나의 태스크만을 담는 것이 더 이해하기 용이하다고 판단했기 때문입니다.
|
| 25 |
+
|
| 26 |
+
|
| 27 |
+
|
| 28 |
+
저희는 diffusion 모델의 대표적인 태스크들을 다루는 공식 예제를 제공하고 있습니다. *공식* 예제는 현재 진행형으로 `diffusers` 관리자들(maintainers)에 의해 관리되고 있습니다. 또한 저희는 앞서 정의한 저희의 철학을 엄격하게 따르고자 노력하고 있습니다. 혹시 여러분께서 이러한 예시가 반드시 필요하다고 생각되신다면, 언제든지 [Feature Request](https://github.com/huggingface/diffusers/issues/new?assignees=&labels=&template=feature_request.md&title=) 혹은 직접 [Pull Request](https://github.com/huggingface/diffusers/compare)를 주시기 바랍니다. 저희는 언제나 환영입니다!
|
| 29 |
+
|
| 30 |
+
학습 예시들은 다양한 태스크들에 대해 diffusion 모델을 사전학습(pretrain)하거나 파인튜닝(fine-tuning)하는 법을 보여줍니다. 현재 다음과 같은 예제들을 지원하고 있습니다.
|
| 31 |
+
|
| 32 |
+
- [Unconditional Training](./unconditional_training)
|
| 33 |
+
- [Text-to-Image Training](./text2image)
|
| 34 |
+
- [Text Inversion](./text_inversion)
|
| 35 |
+
- [Dreambooth](./dreambooth)
|
| 36 |
+
|
| 37 |
+
memory-efficient attention 연산을 수행하기 위해, 가능하면 [xFormers](../optimization/xformers)를 설치해주시기 바랍니다. 이를 통해 학습 속도를 늘리고 메모리에 대한 부담을 줄일 수 있습니다.
|
| 38 |
+
|
| 39 |
+
| Task | 🤗 Accelerate | 🤗 Datasets | Colab
|
| 40 |
+
|---|---|:---:|:---:|
|
| 41 |
+
| [**Unconditional Image Generation**](./unconditional_training) | ✅ | ✅ | [](https://colab.research.google.com/github/huggingface/notebooks/blob/main/diffusers/training_example.ipynb)
|
| 42 |
+
| [**Text-to-Image fine-tuning**](./text2image) | �� | ✅ |
|
| 43 |
+
| [**Textual Inversion**](./text_inversion) | ✅ | - | [](https://colab.research.google.com/github/huggingface/notebooks/blob/main/diffusers/sd_textual_inversion_training.ipynb)
|
| 44 |
+
| [**Dreambooth**](./dreambooth) | ✅ | - | [](https://colab.research.google.com/github/huggingface/notebooks/blob/main/diffusers/sd_dreambooth_training.ipynb)
|
| 45 |
+
| [**Training with LoRA**](./lora) | ✅ | - | - |
|
| 46 |
+
| [**ControlNet**](./controlnet) | ✅ | ✅ | - |
|
| 47 |
+
| [**InstructPix2Pix**](./instructpix2pix) | ✅ | ✅ | - |
|
| 48 |
+
| [**Custom Diffusion**](./custom_diffusion) | ✅ | ✅ | - |
|
| 49 |
+
|
| 50 |
+
|
| 51 |
+
## 커뮤니티
|
| 52 |
+
|
| 53 |
+
공식 예제 외에도 **커뮤니티 예제** 역시 제공하고 있습니다. 해당 예제들은 우리의 커뮤니티에 의해 관리됩니다. 커뮤니티 예쩨는 학습 예시나 추론 파이프라인으로 구성될 수 있습니다. 이러한 커뮤니티 예시들의 경우, 앞서 정의했던 철학들을 좀 더 관대하게 적용하고 있습니다. 또한 이러한 커뮤니티 예시들의 경우, 모든 이슈들에 대한 유지보수를 보장할 수는 없습니다.
|
| 54 |
+
|
| 55 |
+
유용하긴 하지만, 아직은 대중적이지 못하거나 저희의 철학에 부합하지 않는 예제들은 [community examples](https://github.com/huggingface/diffusers/tree/main/examples/community) 폴더에 담기게 됩니다.
|
| 56 |
+
|
| 57 |
+
**Note**: 커뮤니티 예제는 `diffusers`에 기여(contribution)를 희망하는 분들에게 [아주 좋은 기여 수단](https://github.com/huggingface/diffusers/issues?q=is%3Aopen+is%3Aissue+label%3A%22good+first+issue%22)이 될 수 있습니다.
|
| 58 |
+
|
| 59 |
+
## 주목할 사항들
|
| 60 |
+
|
| 61 |
+
최신 버전의 예시 코드들의 성공적인 구동을 보장하기 위해서는, 반드시 **소스코드를 통해 `diffusers`를 설치해야 하며,** 해당 예시 코드들이 요구하는 디펜던시들 역시 설치해야 합니다. 이를 위해 새로운 가상 환경을 구축하고 다음의 명령어를 실행해야 합니다.
|
| 62 |
+
|
| 63 |
+
```bash
|
| 64 |
+
git clone https://github.com/huggingface/diffusers
|
| 65 |
+
cd diffusers
|
| 66 |
+
pip install .
|
| 67 |
+
```
|
| 68 |
+
|
| 69 |
+
그 다음 `cd` 명령어를 통해 해당 예제 디렉토리에 접근해서 다음 명령어를 실행하면 됩니다.
|
| 70 |
+
|
| 71 |
+
```bash
|
| 72 |
+
pip install -r requirements.txt
|
| 73 |
+
```
|
tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/training/text2image.md
ADDED
|
@@ -0,0 +1,224 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2024 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
|
| 14 |
+
# Text-to-image
|
| 15 |
+
|
| 16 |
+
<Tip warning={true}>
|
| 17 |
+
|
| 18 |
+
text-to-image 파인튜닝 스크립트는 experimental 상태입니다. 과적합하기 쉽고 치명적인 망각과 같은 문제에 부딪히기 쉽습니다. 자체 데이터셋에서 최상의 결과를 얻으려면 다양한 하이퍼파라미터를 탐색하는 것이 좋습니다.
|
| 19 |
+
|
| 20 |
+
</Tip>
|
| 21 |
+
|
| 22 |
+
Stable Diffusion과 같은 text-to-image 모델은 텍스트 프롬프트에서 이미지를 생성합니다. 이 가이드는 PyTorch 및 Flax를 사용하여 자체 데이터셋에서 [`CompVis/stable-diffusion-v1-4`](https://huggingface.co/CompVis/stable-diffusion-v1-4) 모델로 파인튜닝하는 방법을 보여줍니다. 이 가이드에 사용된 text-to-image 파인튜닝을 위한 모든 학습 스크립트에 관심이 있는 경우 이 [리포지토리](https://github.com/huggingface/diffusers/tree/main/examples/text_to_image)에서 자세히 찾을 수 있습니다.
|
| 23 |
+
|
| 24 |
+
스크립트를 실행하기 전에, 라이브러리의 학습 dependency들을 설치해야 합니다:
|
| 25 |
+
|
| 26 |
+
```bash
|
| 27 |
+
pip install git+https://github.com/huggingface/diffusers.git
|
| 28 |
+
pip install -U -r requirements.txt
|
| 29 |
+
```
|
| 30 |
+
|
| 31 |
+
그리고 [🤗Accelerate](https://github.com/huggingface/accelerate/) 환경을 초기화합니다:
|
| 32 |
+
|
| 33 |
+
```bash
|
| 34 |
+
accelerate config
|
| 35 |
+
```
|
| 36 |
+
|
| 37 |
+
리포지토리를 이미 복제한 경우, 이 단계를 수행할 필요가 없습니다. 대신, 로컬 체크아웃 경로를 학습 스크립트에 명시할 수 있으며 거기에서 로드됩니다.
|
| 38 |
+
|
| 39 |
+
### 하드웨어 요구 사항
|
| 40 |
+
|
| 41 |
+
`gradient_checkpointing` 및 `mixed_precision`을 사용하면 단일 24GB GPU에서 모델을 파인튜닝할 수 있습니다. 더 높은 `batch_size`와 더 빠른 훈련을 위해서는 GPU 메모리가 30GB 이상인 GPU를 사용하는 것이 좋습니다. TPU 또는 GPU에서 파인튜닝을 위해 JAX나 Flax를 사용할 수도 있습니다. 자세한 내용은 [아래](#flax-jax-finetuning)를 참조하세요.
|
| 42 |
+
|
| 43 |
+
xFormers로 memory efficient attention을 활성화하여 메모리 사용량 훨씬 더 줄일 수 있습니다. [xFormers가 설치](./optimization/xformers)되어 있는지 확인하고 `--enable_xformers_memory_efficient_attention`를 학습 스크립트에 명시합니다.
|
| 44 |
+
|
| 45 |
+
xFormers는 Flax에 사용할 수 없습니다.
|
| 46 |
+
|
| 47 |
+
## Hub에 모델 업로드하기
|
| 48 |
+
|
| 49 |
+
학습 스크립트에 다음 인수를 추가하여 모델을 허브에 저장합니다:
|
| 50 |
+
|
| 51 |
+
```bash
|
| 52 |
+
--push_to_hub
|
| 53 |
+
```
|
| 54 |
+
|
| 55 |
+
|
| 56 |
+
## 체크포인트 저장 및 불러오기
|
| 57 |
+
|
| 58 |
+
학습 중 발생할 수 있는 일에 대비하여 정기적으로 체크포인트를 저장해 두는 것이 좋습니다. 체크포인트를 저장하려면 학습 스크립트에 다음 인수를 명시합니다.
|
| 59 |
+
|
| 60 |
+
```bash
|
| 61 |
+
--checkpointing_steps=500
|
| 62 |
+
```
|
| 63 |
+
|
| 64 |
+
500스텝마다 전체 학습 state가 'output_dir'의 하위 폴더에 저장됩니다. 체크포인트는 'checkpoint-'에 지금까지 학습된 step 수입니다. 예를 들어 'checkpoint-1500'은 1500 학습 step 후에 저장된 체크포인트입니다.
|
| 65 |
+
|
| 66 |
+
학습을 재개하기 위해 체크포인트를 불러오려면 '--resume_from_checkpoint' 인수를 학습 스크립트에 명시하고 재개할 체크포인트를 지정하십시오. 예를 들어 다음 인수는 1500개의 학습 step 후에 저장된 체크포인트에서부터 훈련을 재개합니다.
|
| 67 |
+
|
| 68 |
+
```bash
|
| 69 |
+
--resume_from_checkpoint="checkpoint-1500"
|
| 70 |
+
```
|
| 71 |
+
|
| 72 |
+
## 파인튜닝
|
| 73 |
+
|
| 74 |
+
<frameworkcontent>
|
| 75 |
+
<pt>
|
| 76 |
+
다음과 같이 [Naruto BLIP 캡션](https://huggingface.co/datasets/lambdalabs/naruto-blip-captions) 데이터셋에서 파인튜닝 실행을 위해 [PyTorch 학습 스크립트](https://github.com/huggingface/diffusers/blob/main/examples/text_to_image/train_text_to_image.py)를 실행합니다:
|
| 77 |
+
|
| 78 |
+
|
| 79 |
+
```bash
|
| 80 |
+
export MODEL_NAME="CompVis/stable-diffusion-v1-4"
|
| 81 |
+
export dataset_name="lambdalabs/naruto-blip-captions"
|
| 82 |
+
|
| 83 |
+
accelerate launch train_text_to_image.py \
|
| 84 |
+
--pretrained_model_name_or_path=$MODEL_NAME \
|
| 85 |
+
--dataset_name=$dataset_name \
|
| 86 |
+
--use_ema \
|
| 87 |
+
--resolution=512 --center_crop --random_flip \
|
| 88 |
+
--train_batch_size=1 \
|
| 89 |
+
--gradient_accumulation_steps=4 \
|
| 90 |
+
--gradient_checkpointing \
|
| 91 |
+
--mixed_precision="fp16" \
|
| 92 |
+
--max_train_steps=15000 \
|
| 93 |
+
--learning_rate=1e-05 \
|
| 94 |
+
--max_grad_norm=1 \
|
| 95 |
+
--lr_scheduler="constant" --lr_warmup_steps=0 \
|
| 96 |
+
--output_dir="sd-naruto-model"
|
| 97 |
+
```
|
| 98 |
+
|
| 99 |
+
자체 데이터셋으로 파인튜닝하려면 🤗 [Datasets](https://huggingface.co/docs/datasets/index)에서 요구하는 ���식에 따라 데이터셋을 준비하세요. [데이터셋을 허브에 업로드](https://huggingface.co/docs/datasets/image_dataset#upload-dataset-to-the-hub)하거나 [파일들이 있는 로컬 폴더를 준비](https ://huggingface.co/docs/datasets/image_dataset#imagefolder)할 수 있습니다.
|
| 100 |
+
|
| 101 |
+
사용자 커스텀 loading logic을 사용하려면 스크립트를 수정하십시오. 도움이 되도록 코드의 적절한 위치에 포인터를 남겼습니다. 🤗 아래 예제 스크립트는 `TRAIN_DIR`의 로컬 데이터셋으로를 파인튜닝하는 방법과 `OUTPUT_DIR`에서 모델을 저장할 위치를 보여줍니다:
|
| 102 |
+
|
| 103 |
+
|
| 104 |
+
```bash
|
| 105 |
+
export MODEL_NAME="CompVis/stable-diffusion-v1-4"
|
| 106 |
+
export TRAIN_DIR="path_to_your_dataset"
|
| 107 |
+
export OUTPUT_DIR="path_to_save_model"
|
| 108 |
+
|
| 109 |
+
accelerate launch train_text_to_image.py \
|
| 110 |
+
--pretrained_model_name_or_path=$MODEL_NAME \
|
| 111 |
+
--train_data_dir=$TRAIN_DIR \
|
| 112 |
+
--use_ema \
|
| 113 |
+
--resolution=512 --center_crop --random_flip \
|
| 114 |
+
--train_batch_size=1 \
|
| 115 |
+
--gradient_accumulation_steps=4 \
|
| 116 |
+
--gradient_checkpointing \
|
| 117 |
+
--mixed_precision="fp16" \
|
| 118 |
+
--max_train_steps=15000 \
|
| 119 |
+
--learning_rate=1e-05 \
|
| 120 |
+
--max_grad_norm=1 \
|
| 121 |
+
--lr_scheduler="constant" --lr_warmup_steps=0 \
|
| 122 |
+
--output_dir=${OUTPUT_DIR}
|
| 123 |
+
```
|
| 124 |
+
|
| 125 |
+
</pt>
|
| 126 |
+
<jax>
|
| 127 |
+
[@duongna211](https://github.com/duongna21)의 기여로, Flax를 사용해 TPU 및 GPU에서 Stable Diffusion 모델을 더 빠르게 학습할 수 있습니다. 이는 TPU 하드웨어에서 매우 효율적이지만 GPU에서도 훌륭하게 작동합니다. Flax 학습 스크립트는 gradient checkpointing나 gradient accumulation과 같은 기능을 아직 지원하지 않으므로 메모리가 30GB 이상인 GPU 또는 TPU v3가 필요합니다.
|
| 128 |
+
|
| 129 |
+
스크립트를 실행하기 전에 요구 사항이 설치되어 있는지 확인하십시오:
|
| 130 |
+
|
| 131 |
+
```bash
|
| 132 |
+
pip install -U -r requirements_flax.txt
|
| 133 |
+
```
|
| 134 |
+
|
| 135 |
+
그러면 다음과 같이 [Flax 학습 스크립트](https://github.com/huggingface/diffusers/blob/main/examples/text_to_image/train_text_to_image_flax.py)를 실행할 수 있습니다.
|
| 136 |
+
|
| 137 |
+
```bash
|
| 138 |
+
export MODEL_NAME="stable-diffusion-v1-5/stable-diffusion-v1-5"
|
| 139 |
+
export dataset_name="lambdalabs/naruto-blip-captions"
|
| 140 |
+
|
| 141 |
+
python train_text_to_image_flax.py \
|
| 142 |
+
--pretrained_model_name_or_path=$MODEL_NAME \
|
| 143 |
+
--dataset_name=$dataset_name \
|
| 144 |
+
--resolution=512 --center_crop --random_flip \
|
| 145 |
+
--train_batch_size=1 \
|
| 146 |
+
--max_train_steps=15000 \
|
| 147 |
+
--learning_rate=1e-05 \
|
| 148 |
+
--max_grad_norm=1 \
|
| 149 |
+
--output_dir="sd-naruto-model"
|
| 150 |
+
```
|
| 151 |
+
|
| 152 |
+
자체 데이터셋으로 파인튜닝하려면 🤗 [Datasets](https://huggingface.co/docs/datasets/index)에서 요구하는 형식에 따라 데이터셋을 준비하세요. [데이터셋을 허브에 업로드](https://huggingface.co/docs/datasets/image_dataset#upload-dataset-to-the-hub)하거나 [파일들이 있는 로컬 폴더를 준비](https ://huggingface.co/docs/datasets/image_dataset#imagefolder)할 수 있습니다.
|
| 153 |
+
|
| 154 |
+
사용자 커스텀 loading logic을 사용하려면 스크립트를 수정하십시오. 도움이 되도록 코드의 적절한 위치에 포인터를 남겼습니다. 🤗 아래 예제 스크립트는 `TRAIN_DIR`의 로컬 데이터셋으로를 파인튜닝하는 방법을 보여줍니다:
|
| 155 |
+
|
| 156 |
+
```bash
|
| 157 |
+
export MODEL_NAME="duongna/stable-diffusion-v1-4-flax"
|
| 158 |
+
export TRAIN_DIR="path_to_your_dataset"
|
| 159 |
+
|
| 160 |
+
python train_text_to_image_flax.py \
|
| 161 |
+
--pretrained_model_name_or_path=$MODEL_NAME \
|
| 162 |
+
--train_data_dir=$TRAIN_DIR \
|
| 163 |
+
--resolution=512 --center_crop --random_flip \
|
| 164 |
+
--train_batch_size=1 \
|
| 165 |
+
--mixed_precision="fp16" \
|
| 166 |
+
--max_train_steps=15000 \
|
| 167 |
+
--learning_rate=1e-05 \
|
| 168 |
+
--max_grad_norm=1 \
|
| 169 |
+
--output_dir="sd-naruto-model"
|
| 170 |
+
```
|
| 171 |
+
</jax>
|
| 172 |
+
</frameworkcontent>
|
| 173 |
+
|
| 174 |
+
## LoRA
|
| 175 |
+
|
| 176 |
+
Text-to-image 모델 파인튜닝을 위해, 대규모 모델 학습을 가속화하기 위한 파인튜닝 기술인 LoRA(Low-Rank Adaptation of Large Language Models)를 사용할 수 있습니다. 자세한 내용은 [LoRA 학습](lora#text-to-image) 가이드를 참조하세요.
|
| 177 |
+
|
| 178 |
+
## 추론
|
| 179 |
+
|
| 180 |
+
허브의 모델 경로 또는 모델 이름을 [`StableDiffusionPipeline`]에 전달하여 추론을 위해 파인 튜닝된 모델을 불러올 수 있습니다:
|
| 181 |
+
|
| 182 |
+
<frameworkcontent>
|
| 183 |
+
<pt>
|
| 184 |
+
```python
|
| 185 |
+
from diffusers import StableDiffusionPipeline
|
| 186 |
+
|
| 187 |
+
model_path = "path_to_saved_model"
|
| 188 |
+
pipe = StableDiffusionPipeline.from_pretrained(model_path, torch_dtype=torch.float16)
|
| 189 |
+
pipe.to("cuda")
|
| 190 |
+
|
| 191 |
+
image = pipe(prompt="yoda").images[0]
|
| 192 |
+
image.save("yoda-naruto.png")
|
| 193 |
+
```
|
| 194 |
+
</pt>
|
| 195 |
+
<jax>
|
| 196 |
+
```python
|
| 197 |
+
import jax
|
| 198 |
+
import numpy as np
|
| 199 |
+
from flax.jax_utils import replicate
|
| 200 |
+
from flax.training.common_utils import shard
|
| 201 |
+
from diffusers import FlaxStableDiffusionPipeline
|
| 202 |
+
|
| 203 |
+
model_path = "path_to_saved_model"
|
| 204 |
+
pipe, params = FlaxStableDiffusionPipeline.from_pretrained(model_path, dtype=jax.numpy.bfloat16)
|
| 205 |
+
|
| 206 |
+
prompt = "yoda naruto"
|
| 207 |
+
prng_seed = jax.random.PRNGKey(0)
|
| 208 |
+
num_inference_steps = 50
|
| 209 |
+
|
| 210 |
+
num_samples = jax.device_count()
|
| 211 |
+
prompt = num_samples * [prompt]
|
| 212 |
+
prompt_ids = pipeline.prepare_inputs(prompt)
|
| 213 |
+
|
| 214 |
+
# shard inputs and rng
|
| 215 |
+
params = replicate(params)
|
| 216 |
+
prng_seed = jax.random.split(prng_seed, jax.device_count())
|
| 217 |
+
prompt_ids = shard(prompt_ids)
|
| 218 |
+
|
| 219 |
+
images = pipeline(prompt_ids, params, prng_seed, num_inference_steps, jit=True).images
|
| 220 |
+
images = pipeline.numpy_to_pil(np.asarray(images.reshape((num_samples,) + images.shape[-3:])))
|
| 221 |
+
image.save("yoda-naruto.png")
|
| 222 |
+
```
|
| 223 |
+
</jax>
|
| 224 |
+
</frameworkcontent>
|
tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/training/text_inversion.md
ADDED
|
@@ -0,0 +1,275 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2024 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
|
| 14 |
+
|
| 15 |
+
# Textual-Inversion
|
| 16 |
+
|
| 17 |
+
[[open-in-colab]]
|
| 18 |
+
|
| 19 |
+
[textual-inversion](https://huggingface.co/papers/2208.01618)은 소수의 예시 이미지에서 새로운 콘셉트를 포착하는 기법입니다. 이 기술은 원래 [Latent Diffusion](https://github.com/CompVis/latent-diffusion)에서 시연되었지만, 이후 [Stable Diffusion](https://huggingface.co/docs/diffusers/main/en/conceptual/stable_diffusion)과 같은 유사한 다른 모델에도 적용되었습니다. 학습된 콘셉트는 text-to-image 파이프라인에서 생성된 이미지를 더 잘 제어하는 데 사용할 수 있습니다. 이 모델은 텍스트 인코더의 임베딩 공간에서 새로운 '단어'를 학습하여 개인화된 이미지 생성을 위한 텍스트 프롬프트 내에서 사용됩니다.
|
| 20 |
+
|
| 21 |
+
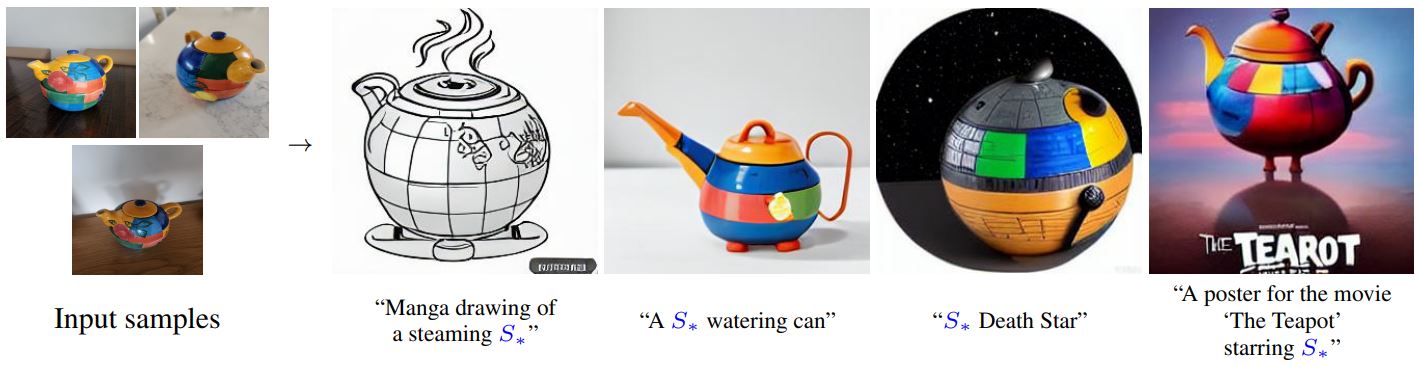
|
| 22 |
+
<small>By using just 3-5 images you can teach new concepts to a model such as Stable Diffusion for personalized image generation <a href="https://github.com/rinongal/textual_inversion">(image source)</a>.</small>
|
| 23 |
+
|
| 24 |
+
이 가이드에서는 textual-inversion으로 [`stable-diffusion-v1-5/stable-diffusion-v1-5`](https://huggingface.co/stable-diffusion-v1-5/stable-diffusion-v1-5) 모델을 학습하는 방법을 설명합니다. 이 가이드에서 사용된 모든 textual-inversion 학습 스크립트는 [여기](https://github.com/huggingface/diffusers/tree/main/examples/textual_inversion)에서 확인할 수 있습니다. 내부적으로 어떻게 작동하는지 자세히 살펴보고 싶으시다면 해당 링크를 참조해주시기 바랍니다.
|
| 25 |
+
|
| 26 |
+
<Tip>
|
| 27 |
+
|
| 28 |
+
[Stable Diffusion Textual Inversion Concepts Library](https://huggingface.co/sd-concepts-library)에는 커뮤니티에서 제작한 학습된 textual-inversion 모델들이 있습니다. 시간이 지남에 따라 더 많은 콘셉트들이 추가되어 유용한 리소스로 성장할 것입니다!
|
| 29 |
+
|
| 30 |
+
</Tip>
|
| 31 |
+
|
| 32 |
+
시작하기 전에 학습을 위한 의존성 라이브러리들을 설치해야 합니다:
|
| 33 |
+
|
| 34 |
+
```bash
|
| 35 |
+
pip install diffusers accelerate transformers
|
| 36 |
+
```
|
| 37 |
+
|
| 38 |
+
의존성 라이브러리들의 설치가 완료되면, [🤗Accelerate](https://github.com/huggingface/accelerate/) 환경을 초기화시킵니다.
|
| 39 |
+
|
| 40 |
+
```bash
|
| 41 |
+
accelerate config
|
| 42 |
+
```
|
| 43 |
+
|
| 44 |
+
별도의 설정없이, 기본 🤗Accelerate 환경을 설정하려면 다음과 같이 하세요:
|
| 45 |
+
|
| 46 |
+
```bash
|
| 47 |
+
accelerate config default
|
| 48 |
+
```
|
| 49 |
+
|
| 50 |
+
또는 사용 중인 환경이 노트북과 같은 대화형 셸을 지원하지 않는다면, 다음과 같이 사용할 수 있습니다:
|
| 51 |
+
|
| 52 |
+
```py
|
| 53 |
+
from accelerate.utils import write_basic_config
|
| 54 |
+
|
| 55 |
+
write_basic_config()
|
| 56 |
+
```
|
| 57 |
+
|
| 58 |
+
마지막으로, Memory-Efficient Attention을 통해 메모리 사용량을 줄이기 위해 [xFormers](https://huggingface.co/docs/diffusers/main/en/training/optimization/xformers)를 설치합니다. xFormers를 설치한 후, 학습 스크립트에 `--enable_xformers_memory_efficient_attention` 인자를 추가합니다. xFormers는 Flax에서 지원되지 않습니다.
|
| 59 |
+
|
| 60 |
+
## 허브에 모델 업로드하기
|
| 61 |
+
|
| 62 |
+
모델을 허브에 저장하려면, 학습 스크립트에 다음 인자를 추가해야 합니다.
|
| 63 |
+
|
| 64 |
+
```bash
|
| 65 |
+
--push_to_hub
|
| 66 |
+
```
|
| 67 |
+
|
| 68 |
+
## 체크포인트 저장 및 불러오기
|
| 69 |
+
|
| 70 |
+
학습중에 모델의 체크포인트를 정기적으로 저장하는 것이 좋습니다. 이렇게 하면 어떤 이유로든 학습이 중단된 경우 저장된 체크포인트에서 학습을 다시 시작할 수 있습니다. 학습 스크립트에 다음 인자를 전달하면 500단계마다 전체 학습 상태가 `output_dir`의 하위 폴더에 체크포인트로서 저장됩니다.
|
| 71 |
+
|
| 72 |
+
```bash
|
| 73 |
+
--checkpointing_steps=500
|
| 74 |
+
```
|
| 75 |
+
|
| 76 |
+
저장된 체크포인트에서 학습을 재개하려면, 학습 스크립트와 재개할 특정 체크포인트에 다음 인자를 전달하세요.
|
| 77 |
+
|
| 78 |
+
```bash
|
| 79 |
+
--resume_from_checkpoint="checkpoint-1500"
|
| 80 |
+
```
|
| 81 |
+
|
| 82 |
+
## 파인 튜닝
|
| 83 |
+
|
| 84 |
+
학습용 데이터셋으로 [고양이 장난감 데이터셋](https://huggingface.co/datasets/diffusers/cat_toy_example)을 다운로드하여 디렉토리에 저장하세요. 여러분만의 고유한 데이터셋을 사용하고자 한다면, [학습용 데이터셋 만들기](https://huggingface.co/docs/diffusers/training/create_dataset) 가이드를 살펴보시기 바랍니다.
|
| 85 |
+
|
| 86 |
+
```py
|
| 87 |
+
from huggingface_hub import snapshot_download
|
| 88 |
+
|
| 89 |
+
local_dir = "./cat"
|
| 90 |
+
snapshot_download(
|
| 91 |
+
"diffusers/cat_toy_example", local_dir=local_dir, repo_type="dataset", ignore_patterns=".gitattributes"
|
| 92 |
+
)
|
| 93 |
+
```
|
| 94 |
+
|
| 95 |
+
모델의 리포지토리 ID(또는 모델 가중치가 포함된 디렉터리 경로)를 `MODEL_NAME` 환경 변수에 할당하고, 해당 값을 [`pretrained_model_name_or_path`](https://huggingface.co/docs/diffusers/en/api/diffusion_pipeline#diffusers.DiffusionPipeline.from_pretrained.pretrained_model_name_or_path) 인자에 전달합니다. 그리고 이미지가 포함된 디렉터리 경로를 `DATA_DIR` 환경 변수에 할당합니다.
|
| 96 |
+
|
| 97 |
+
이제 [학습 스크립트](https://github.com/huggingface/diffusers/blob/main/examples/textual_inversion/textual_inversion.py)를 실행할 수 있습니다. 스크립트는 다음 파일을 생성하고 리포지토리에 저장합니다.
|
| 98 |
+
|
| 99 |
+
- `learned_embeds.bin`
|
| 100 |
+
- `token_identifier.txt`
|
| 101 |
+
- `type_of_concept.txt`.
|
| 102 |
+
|
| 103 |
+
<Tip>
|
| 104 |
+
|
| 105 |
+
💡V100 GPU 1개를 기준으로 전체 학습에는 최대 1시간이 걸립니다. 학습이 완료되기를 기다리는 동안 궁금한 점이 있으면 아래 섹션에서 [textual-inversion이 어떻게 작동하는지](https://huggingface.co/docs/diffusers/training/text_inversion#how-it-works) 자유롭게 확인하세요 !
|
| 106 |
+
|
| 107 |
+
</Tip>
|
| 108 |
+
|
| 109 |
+
<frameworkcontent>
|
| 110 |
+
<pt>
|
| 111 |
+
```bash
|
| 112 |
+
export MODEL_NAME="stable-diffusion-v1-5/stable-diffusion-v1-5"
|
| 113 |
+
export DATA_DIR="./cat"
|
| 114 |
+
|
| 115 |
+
accelerate launch textual_inversion.py \
|
| 116 |
+
--pretrained_model_name_or_path=$MODEL_NAME \
|
| 117 |
+
--train_data_dir=$DATA_DIR \
|
| 118 |
+
--learnable_property="object" \
|
| 119 |
+
--placeholder_token="<cat-toy>" --initializer_token="toy" \
|
| 120 |
+
--resolution=512 \
|
| 121 |
+
--train_batch_size=1 \
|
| 122 |
+
--gradient_accumulation_steps=4 \
|
| 123 |
+
--max_train_steps=3000 \
|
| 124 |
+
--learning_rate=5.0e-04 --scale_lr \
|
| 125 |
+
--lr_scheduler="constant" \
|
| 126 |
+
--lr_warmup_steps=0 \
|
| 127 |
+
--output_dir="textual_inversion_cat" \
|
| 128 |
+
--push_to_hub
|
| 129 |
+
```
|
| 130 |
+
|
| 131 |
+
<Tip>
|
| 132 |
+
|
| 133 |
+
💡학습 성능을 올리기 위해, 플레이스홀더 토큰(`<cat-toy>`)을 (단일한 임베딩 벡터가 아닌) 복수의 임베딩 벡터로 표현하는 것 역시 고려할 있습니다. 이러한 트릭이 모델이 보다 복잡한 이미지의 스타일(앞서 말한 콘셉트)을 더 잘 캡처하는 데 도움이 될 수 있습니다. 복수의 임베딩 벡터 학습을 활성화하려면 다음 옵션을 전달하십시오.
|
| 134 |
+
|
| 135 |
+
```bash
|
| 136 |
+
--num_vectors=5
|
| 137 |
+
```
|
| 138 |
+
|
| 139 |
+
</Tip>
|
| 140 |
+
</pt>
|
| 141 |
+
<jax>
|
| 142 |
+
|
| 143 |
+
TPU에 액세스할 수 있는 경우, [Flax 학습 스크립트](https://github.com/huggingface/diffusers/blob/main/examples/textual_inversion/textual_inversion_flax.py)를 사용하여 더 빠르게 모델을 학습시켜보세요. (물론 GPU에서도 작동합니다.) 동일한 설정에서 Flax 학습 스크립트는 PyTorch 학습 스크립트보다 최소 70% 더 빨라야 합니다! ⚡️
|
| 144 |
+
|
| 145 |
+
시작하기 앞서 Flax에 대한 의존성 라이브러리들을 설치해야 합니다.
|
| 146 |
+
|
| 147 |
+
```bash
|
| 148 |
+
pip install -U -r requirements_flax.txt
|
| 149 |
+
```
|
| 150 |
+
|
| 151 |
+
모델의 리포지토리 ID(또는 모델 가중치가 포함된 디렉터리 경로)를 `MODEL_NAME` 환경 변수에 할당하고, 해당 값을 [`pretrained_model_name_or_path`](https://huggingface.co/docs/diffusers/en/api/diffusion_pipeline#diffusers.DiffusionPipeline.from_pretrained.pretrained_model_name_or_path) 인자에 전달합니다.
|
| 152 |
+
|
| 153 |
+
그런 다음 [학습 스크립트](https://github.com/huggingface/diffusers/blob/main/examples/textual_inversion/textual_inversion_flax.py)를 시작할 수 있습니다.
|
| 154 |
+
|
| 155 |
+
```bash
|
| 156 |
+
export MODEL_NAME="duongna/stable-diffusion-v1-4-flax"
|
| 157 |
+
export DATA_DIR="./cat"
|
| 158 |
+
|
| 159 |
+
python textual_inversion_flax.py \
|
| 160 |
+
--pretrained_model_name_or_path=$MODEL_NAME \
|
| 161 |
+
--train_data_dir=$DATA_DIR \
|
| 162 |
+
--learnable_property="object" \
|
| 163 |
+
--placeholder_token="<cat-toy>" --initializer_token="toy" \
|
| 164 |
+
--resolution=512 \
|
| 165 |
+
--train_batch_size=1 \
|
| 166 |
+
--max_train_steps=3000 \
|
| 167 |
+
--learning_rate=5.0e-04 --scale_lr \
|
| 168 |
+
--output_dir="textual_inversion_cat" \
|
| 169 |
+
--push_to_hub
|
| 170 |
+
```
|
| 171 |
+
</jax>
|
| 172 |
+
</frameworkcontent>
|
| 173 |
+
|
| 174 |
+
### 중간 로깅
|
| 175 |
+
|
| 176 |
+
모델의 학습 진행 상황을 추적하는 데 관심이 있는 경우, 학습 과정에서 생성된 이미지를 저장할 수 있습니다. 학습 스크립트에 다음 인수를 추가하여 중간 로깅을 활성화합니다.
|
| 177 |
+
|
| 178 |
+
- `validation_prompt` : 샘플을 생성하는 데 사용되는 프롬프트(기본값은 `None`으로 설정되며, 이 때 중간 로깅은 비활성화됨)
|
| 179 |
+
- `num_validation_images` : 생성할 샘플 이미지 수
|
| 180 |
+
- `validation_steps` : `validation_prompt`로부터 샘플 이미지를 생성하기 전 스텝의 수
|
| 181 |
+
|
| 182 |
+
```bash
|
| 183 |
+
--validation_prompt="A <cat-toy> backpack"
|
| 184 |
+
--num_validation_images=4
|
| 185 |
+
--validation_steps=100
|
| 186 |
+
```
|
| 187 |
+
|
| 188 |
+
## 추론
|
| 189 |
+
|
| 190 |
+
모델을 학습한 후에는, 해당 모델을 [`StableDiffusionPipeline`]을 사용하여 추론에 사용할 수 있습니다.
|
| 191 |
+
|
| 192 |
+
textual-inversion 스크립트는 기본적으로 textual-inversion을 통해 얻어진 임베딩 벡터만을 저장합니다. 해당 임베딩 벡터들은 텍스트 인코더의 임베딩 행렬에 추가되어 있습습니다.
|
| 193 |
+
|
| 194 |
+
<frameworkcontent>
|
| 195 |
+
<pt>
|
| 196 |
+
<Tip>
|
| 197 |
+
|
| 198 |
+
💡 커뮤니티는 [sd-concepts-library](https://huggingface.co/sd-concepts-library) 라는 대규모의 textual-inversion 임베딩 벡터 라이브러리를 만들었습니다. textual-inversion 임베딩을 밑바닥부터 학습하는 대신, 해당 라이브러리에 본인이 찾는 textual-inversion 임베딩이 이미 추가되어 있지 않은지를 확인하는 것도 좋은 방법이 될 것 같습니다.
|
| 199 |
+
|
| 200 |
+
</Tip>
|
| 201 |
+
|
| 202 |
+
textual-inversion 임베딩 벡터을 불러오기 위해서는, 먼저 해당 임베딩 벡터를 학습할 때 사용한 모델을 불러와야 합니다. 여기서는 [`stable-diffusion-v1-5/stable-diffusion-v1-5`](https://huggingface.co/docs/diffusers/training/stable-diffusion-v1-5/stable-diffusion-v1-5) 모델이 사용되었다고 가정하고 불러오겠습니다.
|
| 203 |
+
|
| 204 |
+
```python
|
| 205 |
+
from diffusers import StableDiffusionPipeline
|
| 206 |
+
import torch
|
| 207 |
+
|
| 208 |
+
model_id = "stable-diffusion-v1-5/stable-diffusion-v1-5"
|
| 209 |
+
pipe = StableDiffusionPipeline.from_pretrained(model_id, torch_dtype=torch.float16).to("cuda")
|
| 210 |
+
```
|
| 211 |
+
|
| 212 |
+
다음으로 `TextualInversionLoaderMixin.load_textual_inversion` 함수를 통해, textual-inversion 임베딩 벡터를 불러와야 합니다. 여기서 우리는 이전의 `<cat-toy>` 예제의 임베딩을 불러올 것입니다.
|
| 213 |
+
|
| 214 |
+
```python
|
| 215 |
+
pipe.load_textual_inversion("sd-concepts-library/cat-toy")
|
| 216 |
+
```
|
| 217 |
+
|
| 218 |
+
이제 플레이스홀더 토큰(`<cat-toy>`)이 잘 동작하는지를 확인하는 파이프라인을 실행할 수 있습니다.
|
| 219 |
+
|
| 220 |
+
```python
|
| 221 |
+
prompt = "A <cat-toy> backpack"
|
| 222 |
+
|
| 223 |
+
image = pipe(prompt, num_inference_steps=50).images[0]
|
| 224 |
+
image.save("cat-backpack.png")
|
| 225 |
+
```
|
| 226 |
+
|
| 227 |
+
`TextualInversionLoaderMixin.load_textual_inversion`은 Diffusers 형식으로 저장된 텍스트 임베딩 벡터를 로드할 수 있을 뿐만 아니라, [Automatic1111](https://github.com/AUTOMATIC1111/stable-diffusion-webui) 형식으로 저장된 임베딩 벡터도 로드할 수 있습니다. 이렇게 하려면, 먼저 [civitAI](https://civitai.com/models/3036?modelVersionId=8387)에서 임베딩 벡터를 다운로드한 다음 로컬에서 불러와야 합니다.
|
| 228 |
+
|
| 229 |
+
```python
|
| 230 |
+
pipe.load_textual_inversion("./charturnerv2.pt")
|
| 231 |
+
```
|
| 232 |
+
</pt>
|
| 233 |
+
<jax>
|
| 234 |
+
|
| 235 |
+
현재 Flax에 대한 `load_textual_inversion` 함수는 없습니다. 따라서 학습 후 textual-inversion 임베딩 벡터가 모델의 일부로서 저장되었는지를 확인해야 합니다. 그런 다음은 다른 Flax 모델과 마찬가지로 실행할 수 있습니다.
|
| 236 |
+
|
| 237 |
+
```python
|
| 238 |
+
import jax
|
| 239 |
+
import numpy as np
|
| 240 |
+
from flax.jax_utils import replicate
|
| 241 |
+
from flax.training.common_utils import shard
|
| 242 |
+
from diffusers import FlaxStableDiffusionPipeline
|
| 243 |
+
|
| 244 |
+
model_path = "path-to-your-trained-model"
|
| 245 |
+
pipeline, params = FlaxStableDiffusionPipeline.from_pretrained(model_path, dtype=jax.numpy.bfloat16)
|
| 246 |
+
|
| 247 |
+
prompt = "A <cat-toy> backpack"
|
| 248 |
+
prng_seed = jax.random.PRNGKey(0)
|
| 249 |
+
num_inference_steps = 50
|
| 250 |
+
|
| 251 |
+
num_samples = jax.device_count()
|
| 252 |
+
prompt = num_samples * [prompt]
|
| 253 |
+
prompt_ids = pipeline.prepare_inputs(prompt)
|
| 254 |
+
|
| 255 |
+
# shard inputs and rng
|
| 256 |
+
params = replicate(params)
|
| 257 |
+
prng_seed = jax.random.split(prng_seed, jax.device_count())
|
| 258 |
+
prompt_ids = shard(prompt_ids)
|
| 259 |
+
|
| 260 |
+
images = pipeline(prompt_ids, params, prng_seed, num_inference_steps, jit=True).images
|
| 261 |
+
images = pipeline.numpy_to_pil(np.asarray(images.reshape((num_samples,) + images.shape[-3:])))
|
| 262 |
+
image.save("cat-backpack.png")
|
| 263 |
+
```
|
| 264 |
+
</jax>
|
| 265 |
+
</frameworkcontent>
|
| 266 |
+
|
| 267 |
+
## 작동 방식
|
| 268 |
+
|
| 269 |
+
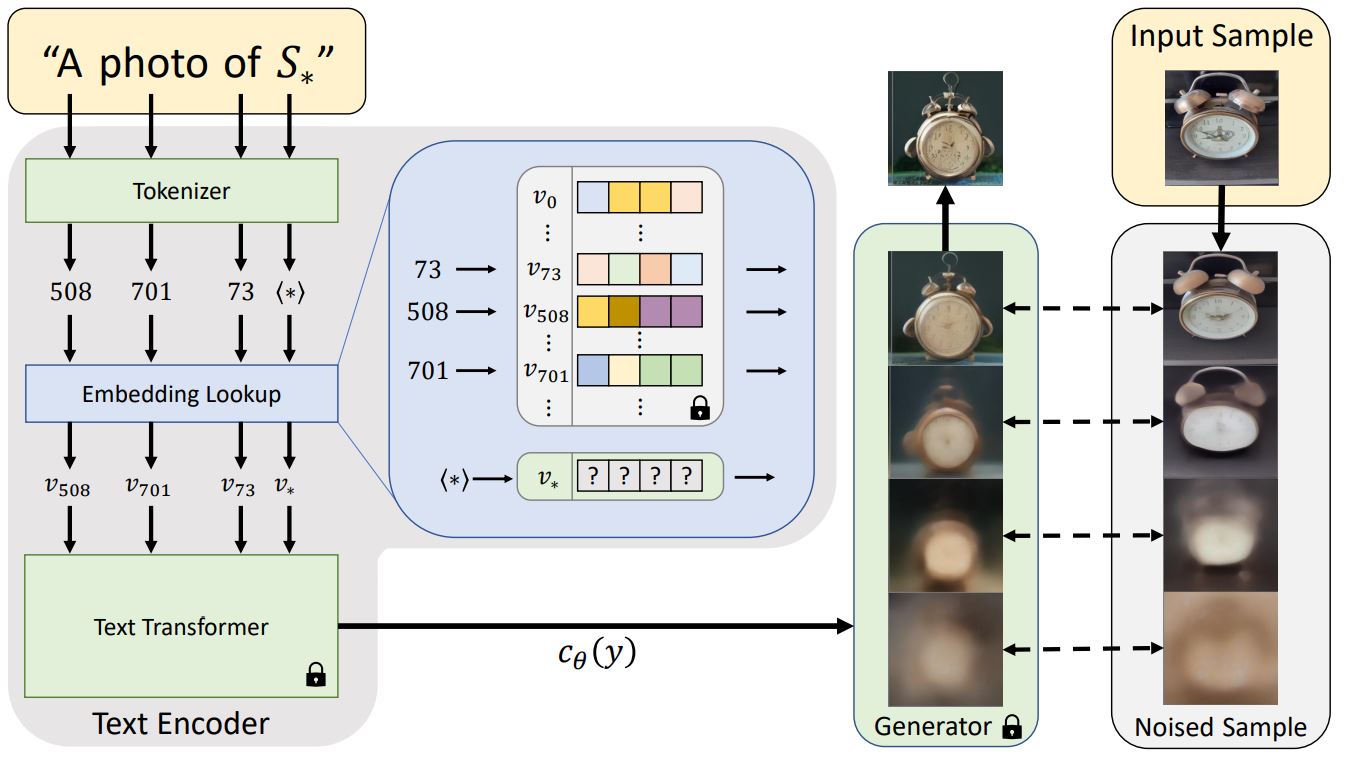
|
| 270 |
+
<small>Architecture overview from the Textual Inversion <a href="https://textual-inversion.github.io/">blog post.</a></small>
|
| 271 |
+
|
| 272 |
+
일반적으로 텍스트 프롬프트는 모델에 전달되기 전에 임베딩으로 토큰화됩니다. textual-inversion은 비슷한 작업을 수행하지만, 위 다이어그램의 특수 토큰 `S*`로부터 새로운 토큰 임베딩 `v*`를 학습합니다. 모델의 아웃풋은 디퓨전 모델을 조정하는 데 사용되며, 디퓨전 모델이 단 몇 개의 예제 이미지에서 신속하고 새로운 콘셉트를 이해하는 데 도움을 줍니다.
|
| 273 |
+
|
| 274 |
+
이를 위해 textual-inversion은 제너레이터 모델과 학습용 이미지의 노이즈 버전을 사용합니다. 제너레이터는 노이즈가 적은 버전의 이미지를 예측하려고 시도하며 토큰 임베딩 `v*`은 제너레이터의 성능에 따라 최적화됩니다. 토큰 임베딩이 새로운 콘셉트를 성공적으로 포착하면 디퓨전 모델에 더 유용한 정보를 제공하고 노이즈가 적은 더 선명한 이미지를 생성하는 데 도움이 됩니다. 이러한 최적화 프로세스는 일반적으로 다양한 프롬프트와 이미지에 수천 번에 노출됨으로써 이루어집니다.
|
| 275 |
+
|
tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/training/unconditional_training.md
ADDED
|
@@ -0,0 +1,144 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2024 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Unconditional 이미지 생성
|
| 14 |
+
|
| 15 |
+
unconditional 이미지 생성은 text-to-image 또는 image-to-image 모델과 달리 텍스트나 이미지에 대한 조건이 없이 학습 데이터 분포와 유사한 이미지만을 생성합니다.
|
| 16 |
+
|
| 17 |
+
<iframe
|
| 18 |
+
src="https://stevhliu-ddpm-butterflies-128.hf.space"
|
| 19 |
+
frameborder="0"
|
| 20 |
+
width="850"
|
| 21 |
+
height="550"
|
| 22 |
+
></iframe>
|
| 23 |
+
|
| 24 |
+
|
| 25 |
+
이 가이드에서는 기존에 존재하던 데이터셋과 자신만의 커스텀 데이터셋에 대해 unconditional image generation 모델을 훈련하는 방법을 설명합니다. 훈련 세부 사항에 대해 더 자세히 알고 싶다면 unconditional image generation을 위한 모든 학습 스크립트를 [여기](https://github.com/huggingface/diffusers/tree/main/examples/unconditional_image_generation)에서 확인할 수 있습니다.
|
| 26 |
+
|
| 27 |
+
스크립트를 실행하기 전, 먼저 의존성 라이브러리들을 설치해야 합니다.
|
| 28 |
+
|
| 29 |
+
```bash
|
| 30 |
+
pip install diffusers[training] accelerate datasets
|
| 31 |
+
```
|
| 32 |
+
|
| 33 |
+
그 다음 🤗 [Accelerate](https://github.com/huggingface/accelerate/) 환경을 초기화합니다.
|
| 34 |
+
|
| 35 |
+
```bash
|
| 36 |
+
accelerate config
|
| 37 |
+
```
|
| 38 |
+
|
| 39 |
+
별도의 설정 없이 기본 설정으로 🤗 [Accelerate](https://github.com/huggingface/accelerate/) 환경을 초기화해봅시다.
|
| 40 |
+
|
| 41 |
+
```bash
|
| 42 |
+
accelerate config default
|
| 43 |
+
```
|
| 44 |
+
|
| 45 |
+
노트북과 같은 대화형 쉘을 지원하지 않는 환경의 경우, 다음과 같이 사용해볼 수도 있습니다.
|
| 46 |
+
|
| 47 |
+
```py
|
| 48 |
+
from accelerate.utils import write_basic_config
|
| 49 |
+
|
| 50 |
+
write_basic_config()
|
| 51 |
+
```
|
| 52 |
+
|
| 53 |
+
## 모델을 허브에 업로드하기
|
| 54 |
+
|
| 55 |
+
학습 스크립트에 다음 인자를 추가하여 허브에 모델을 업로드할 수 있습니다.
|
| 56 |
+
|
| 57 |
+
```bash
|
| 58 |
+
--push_to_hub
|
| 59 |
+
```
|
| 60 |
+
|
| 61 |
+
## 체크포인트 저장하고 불러오기
|
| 62 |
+
|
| 63 |
+
훈련 중 문제가 발생할 경우를 대비하여 체크포인트를 정기적으로 저장하는 것이 좋습니다. 체크포인트를 저장하려면 학습 스크립트에 다음 인자를 전달합니다:
|
| 64 |
+
|
| 65 |
+
```bash
|
| 66 |
+
--checkpointing_steps=500
|
| 67 |
+
```
|
| 68 |
+
|
| 69 |
+
전체 훈련 상태는 500스텝마다 `output_dir`의 하위 폴더에 저장되며, 학습 스크립트에 `--resume_from_checkpoint` 인자를 전달함으로써 체크포인트를 불러오고 훈련을 재개할 수 있습니다.
|
| 70 |
+
|
| 71 |
+
```bash
|
| 72 |
+
--resume_from_checkpoint="checkpoint-1500"
|
| 73 |
+
```
|
| 74 |
+
|
| 75 |
+
## 파인튜닝
|
| 76 |
+
|
| 77 |
+
이제 학습 스크립트를 시작할 준비가 되었습니다! `--dataset_name` 인자에 파인튜닝할 데이터셋 이름을 지정한 다음, `--output_dir` 인자에 지정된 경로로 저장합니다. 본인만의 데이터셋를 사용하려면, [학습용 데이터셋 만들기](create_dataset) 가이드를 참조하세요.
|
| 78 |
+
|
| 79 |
+
학습 스크립트는 `diffusion_pytorch_model.bin` 파일을 생성하고, 그것을 당신의 리포지토리에 저장합니다.
|
| 80 |
+
|
| 81 |
+
<Tip>
|
| 82 |
+
|
| 83 |
+
💡 전체 학습은 V100 GPU 4개를 사용할 경우, 2시간이 소요됩니다.
|
| 84 |
+
|
| 85 |
+
</Tip>
|
| 86 |
+
|
| 87 |
+
예를 들어, [Oxford Flowers](https://huggingface.co/datasets/huggan/flowers-102-categories) 데이터셋을 사용해 파인튜닝할 경우:
|
| 88 |
+
|
| 89 |
+
```bash
|
| 90 |
+
accelerate launch train_unconditional.py \
|
| 91 |
+
--dataset_name="huggan/flowers-102-categories" \
|
| 92 |
+
--resolution=64 \
|
| 93 |
+
--output_dir="ddpm-ema-flowers-64" \
|
| 94 |
+
--train_batch_size=16 \
|
| 95 |
+
--num_epochs=100 \
|
| 96 |
+
--gradient_accumulation_steps=1 \
|
| 97 |
+
--learning_rate=1e-4 \
|
| 98 |
+
--lr_warmup_steps=500 \
|
| 99 |
+
--mixed_precision=no \
|
| 100 |
+
--push_to_hub
|
| 101 |
+
```
|
| 102 |
+
|
| 103 |
+
<div class="flex justify-center">
|
| 104 |
+
<img src="https://user-images.githubusercontent.com/26864830/180248660-a0b143d0-b89a-42c5-8656-2ebf6ece7e52.png"/>
|
| 105 |
+
</div>
|
| 106 |
+
[Naruto](https://huggingface.co/datasets/lambdalabs/naruto-blip-captions) 데이터셋을 사용할 경우:
|
| 107 |
+
|
| 108 |
+
```bash
|
| 109 |
+
accelerate launch train_unconditional.py \
|
| 110 |
+
--dataset_name="lambdalabs/naruto-blip-captions" \
|
| 111 |
+
--resolution=64 \
|
| 112 |
+
--output_dir="ddpm-ema-naruto-64" \
|
| 113 |
+
--train_batch_size=16 \
|
| 114 |
+
--num_epochs=100 \
|
| 115 |
+
--gradient_accumulation_steps=1 \
|
| 116 |
+
--learning_rate=1e-4 \
|
| 117 |
+
--lr_warmup_steps=500 \
|
| 118 |
+
--mixed_precision=no \
|
| 119 |
+
--push_to_hub
|
| 120 |
+
```
|
| 121 |
+
|
| 122 |
+
<div class="flex justify-center">
|
| 123 |
+
<img src="https://user-images.githubusercontent.com/26864830/180248200-928953b4-db38-48db-b0c6-8b740fe6786f.png"/>
|
| 124 |
+
</div>
|
| 125 |
+
|
| 126 |
+
### 여러개의 GPU로 훈련하기
|
| 127 |
+
|
| 128 |
+
`accelerate`을 사용하면 원활한 다중 GPU 훈련이 가능합니다. `accelerate`을 사용하여 분산 훈련을 실행하려면 [여기](https://huggingface.co/docs/accelerate/basic_tutorials/launch) 지침을 따��세요. 다음은 명령어 예제입니다.
|
| 129 |
+
|
| 130 |
+
```bash
|
| 131 |
+
accelerate launch --mixed_precision="fp16" --multi_gpu train_unconditional.py \
|
| 132 |
+
--dataset_name="lambdalabs/naruto-blip-captions" \
|
| 133 |
+
--resolution=64 --center_crop --random_flip \
|
| 134 |
+
--output_dir="ddpm-ema-naruto-64" \
|
| 135 |
+
--train_batch_size=16 \
|
| 136 |
+
--num_epochs=100 \
|
| 137 |
+
--gradient_accumulation_steps=1 \
|
| 138 |
+
--use_ema \
|
| 139 |
+
--learning_rate=1e-4 \
|
| 140 |
+
--lr_warmup_steps=500 \
|
| 141 |
+
--mixed_precision="fp16" \
|
| 142 |
+
--logger="wandb" \
|
| 143 |
+
--push_to_hub
|
| 144 |
+
```
|
tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/tutorials/basic_training.md
ADDED
|
@@ -0,0 +1,402 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2024 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
[[open-in-colab]]
|
| 14 |
+
|
| 15 |
+
|
| 16 |
+
# Diffusion 모델을 학습하기
|
| 17 |
+
|
| 18 |
+
Unconditional 이미지 생성은 학습에 사용된 데이터셋과 유사한 이미지를 생성하는 diffusion 모델에서 인기 있는 어플리케이션입니다. 일반적으로, 가장 좋은 결과는 특정 데이터셋에 사전 훈련된 모델을 파인튜닝하는 것으로 얻을 수 있습니다. 이 [허브](https://huggingface.co/search/full-text?q=unconditional-image-generation&type=model)에서 이러한 많은 체크포인트를 찾을 수 있지만, 만약 마음에 드는 체크포인트를 찾지 못했다면, 언제든지 스스로 학습할 수 있습니다!
|
| 19 |
+
|
| 20 |
+
이 튜토리얼은 나만의 🦋 나비 🦋를 생성하기 위해 [Smithsonian Butterflies](https://huggingface.co/datasets/huggan/smithsonian_butterflies_subset) 데이터셋의 하위 집합에서 [`UNet2DModel`] 모델을 학습하는 방법을 가르쳐줄 것입니다.
|
| 21 |
+
|
| 22 |
+
<Tip>
|
| 23 |
+
|
| 24 |
+
💡 이 학습 튜토리얼은 [Training with 🧨 Diffusers](https://colab.research.google.com/github/huggingface/notebooks/blob/main/diffusers/training_example.ipynb) 노트북 기반으로 합니다. Diffusion 모델의 작동 방식 및 자세한 내용은 노트북을 확인하세요!
|
| 25 |
+
|
| 26 |
+
</Tip>
|
| 27 |
+
|
| 28 |
+
시작 전에, 🤗 Datasets을 불러오고 전처리하기 위해 데이터셋이 설치되어 있는지 다수 GPU에서 학습을 간소화하기 위해 🤗 Accelerate 가 설치되어 있는지 확인하세요. 그 후 학습 메트릭을 시각화하기 위해 [TensorBoard](https://www.tensorflow.org/tensorboard)를 또한 설치하세요. (또한 학습 추적을 위해 [Weights & Biases](https://docs.wandb.ai/)를 사용할 수 있습니다.)
|
| 29 |
+
|
| 30 |
+
```bash
|
| 31 |
+
!pip install diffusers[training]
|
| 32 |
+
```
|
| 33 |
+
|
| 34 |
+
커뮤니티에 모델을 공유할 것을 권장하며, 이를 위해서 Hugging Face 계정에 로그인을 해야 합니다. (계정이 없다면 [여기](https://hf.co/join)에서 만들 수 있습니다.) 노트북에서 로그인할 수 있으며 메시지가 표시되면 토큰을 입력할 수 있습니다.
|
| 35 |
+
|
| 36 |
+
```py
|
| 37 |
+
>>> from huggingface_hub import notebook_login
|
| 38 |
+
|
| 39 |
+
>>> notebook_login()
|
| 40 |
+
```
|
| 41 |
+
|
| 42 |
+
또는 터미널로 로그인할 수 있습니다:
|
| 43 |
+
|
| 44 |
+
```bash
|
| 45 |
+
huggingface-cli login
|
| 46 |
+
```
|
| 47 |
+
|
| 48 |
+
모델 체크포인트가 상당히 크기 때문에 [Git-LFS](https://git-lfs.com/)에서 대용량 파일의 버전 관리를 할 수 있습니다.
|
| 49 |
+
|
| 50 |
+
```bash
|
| 51 |
+
!sudo apt -qq install git-lfs
|
| 52 |
+
!git config --global credential.helper store
|
| 53 |
+
```
|
| 54 |
+
|
| 55 |
+
|
| 56 |
+
## 학습 구성
|
| 57 |
+
|
| 58 |
+
편의를 위해 학습 파라미터들을 포함한 `TrainingConfig` 클래스를 생성합니다 (자유롭게 조정 가능):
|
| 59 |
+
|
| 60 |
+
```py
|
| 61 |
+
>>> from dataclasses import dataclass
|
| 62 |
+
|
| 63 |
+
|
| 64 |
+
>>> @dataclass
|
| 65 |
+
... class TrainingConfig:
|
| 66 |
+
... image_size = 128 # 생성되는 이미지 해상도
|
| 67 |
+
... train_batch_size = 16
|
| 68 |
+
... eval_batch_size = 16 # 평가 동안에 샘플링할 이미지 수
|
| 69 |
+
... num_epochs = 50
|
| 70 |
+
... gradient_accumulation_steps = 1
|
| 71 |
+
... learning_rate = 1e-4
|
| 72 |
+
... lr_warmup_steps = 500
|
| 73 |
+
... save_image_epochs = 10
|
| 74 |
+
... save_model_epochs = 30
|
| 75 |
+
... mixed_precision = "fp16" # `no`는 float32, 자동 혼합 정밀도를 위한 `fp16`
|
| 76 |
+
... output_dir = "ddpm-butterflies-128" # 로컬 및 HF Hub에 저장되는 모델명
|
| 77 |
+
|
| 78 |
+
... push_to_hub = True # 저장된 모델을 HF Hub에 업로드할지 여부
|
| 79 |
+
... hub_private_repo = None
|
| 80 |
+
... overwrite_output_dir = True # 노트북을 다시 실행할 때 이전 모델에 덮어씌울지
|
| 81 |
+
... seed = 0
|
| 82 |
+
|
| 83 |
+
|
| 84 |
+
>>> config = TrainingConfig()
|
| 85 |
+
```
|
| 86 |
+
|
| 87 |
+
|
| 88 |
+
## 데이터셋 불러오기
|
| 89 |
+
|
| 90 |
+
🤗 Datasets 라이브러리와 [Smithsonian Butterflies](https://huggingface.co/datasets/huggan/smithsonian_butterflies_subset) 데이터셋을 쉽게 불러올 수 있습니다.
|
| 91 |
+
|
| 92 |
+
```py
|
| 93 |
+
>>> from datasets import load_dataset
|
| 94 |
+
|
| 95 |
+
>>> config.dataset_name = "huggan/smithsonian_butterflies_subset"
|
| 96 |
+
>>> dataset = load_dataset(config.dataset_name, split="train")
|
| 97 |
+
```
|
| 98 |
+
|
| 99 |
+
💡[HugGan Community Event](https://huggingface.co/huggan) 에서 추가의 데이터셋을 찾거나 로컬의 [`ImageFolder`](https://huggingface.co/docs/datasets/image_dataset#imagefolder)를 만듦으로써 나만의 데이터셋을 사용할 수 있습니다. HugGan Community Event 에 가져온 데이터셋의 경우 리포지토리의 id로 `config.dataset_name` 을 설정하고, 나만의 이미지를 사용하는 경우 `imagefolder` 를 설정합니다.
|
| 100 |
+
|
| 101 |
+
🤗 Datasets은 [`~datasets.Image`] 기능을 사용해 자동으로 이미지 데이터를 디코딩하고 [`PIL.Image`](https://pillow.readthedocs.io/en/stable/reference/Image.html)로 불러옵니다. 이를 시각화 해보면:
|
| 102 |
+
|
| 103 |
+
```py
|
| 104 |
+
>>> import matplotlib.pyplot as plt
|
| 105 |
+
|
| 106 |
+
>>> fig, axs = plt.subplots(1, 4, figsize=(16, 4))
|
| 107 |
+
>>> for i, image in enumerate(dataset[:4]["image"]):
|
| 108 |
+
... axs[i].imshow(image)
|
| 109 |
+
... axs[i].set_axis_off()
|
| 110 |
+
>>> fig.show()
|
| 111 |
+
```
|
| 112 |
+
|
| 113 |
+

|
| 114 |
+
|
| 115 |
+
이미지는 모두 다른 사이즈이기 때문에, 우선 전처리가 필요합니다:
|
| 116 |
+
|
| 117 |
+
- `Resize` 는 `config.image_size` 에 정의된 이미지 사이즈로 변경합니다.
|
| 118 |
+
- `RandomHorizontalFlip` 은 랜덤적으로 이미지를 미러링하여 데이터셋을 보강합니다.
|
| 119 |
+
- `Normalize` 는 모델이 예상하는 [-1, 1] 범위로 픽셀 값을 재조정 하는데 중요합니다.
|
| 120 |
+
|
| 121 |
+
```py
|
| 122 |
+
>>> from torchvision import transforms
|
| 123 |
+
|
| 124 |
+
>>> preprocess = transforms.Compose(
|
| 125 |
+
... [
|
| 126 |
+
... transforms.Resize((config.image_size, config.image_size)),
|
| 127 |
+
... transforms.RandomHorizontalFlip(),
|
| 128 |
+
... transforms.ToTensor(),
|
| 129 |
+
... transforms.Normalize([0.5], [0.5]),
|
| 130 |
+
... ]
|
| 131 |
+
... )
|
| 132 |
+
```
|
| 133 |
+
|
| 134 |
+
학습 도중에 `preprocess` 함수를 적용하려면 🤗 Datasets의 [`~datasets.Dataset.set_transform`] 방법이 사용됩니다.
|
| 135 |
+
|
| 136 |
+
```py
|
| 137 |
+
>>> def transform(examples):
|
| 138 |
+
... images = [preprocess(image.convert("RGB")) for image in examples["image"]]
|
| 139 |
+
... return {"images": images}
|
| 140 |
+
|
| 141 |
+
|
| 142 |
+
>>> dataset.set_transform(transform)
|
| 143 |
+
```
|
| 144 |
+
|
| 145 |
+
이미지의 크기가 조정되었는지 확인하기 위해 이미지를 다시 시각화해보세요. 이제 [DataLoader](https://pytorch.org/docs/stable/data#torch.utils.data.DataLoader)에 데이터셋을 포함해 학습할 준비가 되었습니다!
|
| 146 |
+
|
| 147 |
+
```py
|
| 148 |
+
>>> import torch
|
| 149 |
+
|
| 150 |
+
>>> train_dataloader = torch.utils.data.DataLoader(dataset, batch_size=config.train_batch_size, shuffle=True)
|
| 151 |
+
```
|
| 152 |
+
|
| 153 |
+
|
| 154 |
+
## UNet2DModel 생성하기
|
| 155 |
+
|
| 156 |
+
🧨 Diffusers에 사전학습된 모델들은 모델 클래스에서 원하는 파라미터로 쉽게 생성할 수 있습니다. 예를 들어, [`UNet2DModel`]를 생성하려면:
|
| 157 |
+
|
| 158 |
+
```py
|
| 159 |
+
>>> from diffusers import UNet2DModel
|
| 160 |
+
|
| 161 |
+
>>> model = UNet2DModel(
|
| 162 |
+
... sample_size=config.image_size, # 타겟 이미지 해상도
|
| 163 |
+
... in_channels=3, # 입력 채널 수, RGB 이미지에서 3
|
| 164 |
+
... out_channels=3, # 출력 채널 수
|
| 165 |
+
... layers_per_block=2, # UNet 블럭당 몇 개의 ResNet 레이어가 사용되는지
|
| 166 |
+
... block_out_channels=(128, 128, 256, 256, 512, 512), # 각 UNet 블럭을 위한 출력 채널 수
|
| 167 |
+
... down_block_types=(
|
| 168 |
+
... "DownBlock2D", # 일반적인 ResNet 다운샘플링 블럭
|
| 169 |
+
... "DownBlock2D",
|
| 170 |
+
... "DownBlock2D",
|
| 171 |
+
... "DownBlock2D",
|
| 172 |
+
... "AttnDownBlock2D", # spatial self-attention이 포함된 일반적인 ResNet 다운샘플링 블럭
|
| 173 |
+
... "DownBlock2D",
|
| 174 |
+
... ),
|
| 175 |
+
... up_block_types=(
|
| 176 |
+
... "UpBlock2D", # 일반적인 ResNet 업샘플링 블럭
|
| 177 |
+
... "AttnUpBlock2D", # spatial self-attention이 포함된 일반적인 ResNet 업샘플링 블럭
|
| 178 |
+
... "UpBlock2D",
|
| 179 |
+
... "UpBlock2D",
|
| 180 |
+
... "UpBlock2D",
|
| 181 |
+
... "UpBlock2D",
|
| 182 |
+
... ),
|
| 183 |
+
... )
|
| 184 |
+
```
|
| 185 |
+
|
| 186 |
+
샘플의 이미지 크기와 모델 출력 크기가 맞는지 빠르게 확인하기 위한 좋은 아이디어가 있습니다:
|
| 187 |
+
|
| 188 |
+
```py
|
| 189 |
+
>>> sample_image = dataset[0]["images"].unsqueeze(0)
|
| 190 |
+
>>> print("Input shape:", sample_image.shape)
|
| 191 |
+
Input shape: torch.Size([1, 3, 128, 128])
|
| 192 |
+
|
| 193 |
+
>>> print("Output shape:", model(sample_image, timestep=0).sample.shape)
|
| 194 |
+
Output shape: torch.Size([1, 3, 128, 128])
|
| 195 |
+
```
|
| 196 |
+
|
| 197 |
+
훌륭해요! 다음, 이미지에 약간의 노이즈를 더하기 위해 스케줄러가 필요합니다.
|
| 198 |
+
|
| 199 |
+
|
| 200 |
+
## 스케줄러 생성하기
|
| 201 |
+
|
| 202 |
+
스케줄러는 모델을 학습 또는 추론에 사용하는지에 따라 다르게 작동합니다. 추론시에, 스케줄러는 노이즈로부터 이미지를 생성합니다. 학습시 스케줄러는 diffusion 과정에서의 특정 포인트로부터 모델의 출력 또는 샘플을 가져와 *노이즈 스케줄* 과 *업데이트 규칙*에 따라 이미지에 노이즈를 적용합니다.
|
| 203 |
+
|
| 204 |
+
`DDPMScheduler`를 보면 이전으로부터 `sample_image`에 랜덤한 노이즈를 더하는 `add_noise` 메서드를 사용합니다:
|
| 205 |
+
|
| 206 |
+
```py
|
| 207 |
+
>>> import torch
|
| 208 |
+
>>> from PIL import Image
|
| 209 |
+
>>> from diffusers import DDPMScheduler
|
| 210 |
+
|
| 211 |
+
>>> noise_scheduler = DDPMScheduler(num_train_timesteps=1000)
|
| 212 |
+
>>> noise = torch.randn(sample_image.shape)
|
| 213 |
+
>>> timesteps = torch.LongTensor([50])
|
| 214 |
+
>>> noisy_image = noise_scheduler.add_noise(sample_image, noise, timesteps)
|
| 215 |
+
|
| 216 |
+
>>> Image.fromarray(((noisy_image.permute(0, 2, 3, 1) + 1.0) * 127.5).type(torch.uint8).numpy()[0])
|
| 217 |
+
```
|
| 218 |
+
|
| 219 |
+
|
| 220 |
+
|
| 221 |
+
모델의 학습 목적은 이미지에 더해진 노이즈를 예측하�� 것입니다. 이 단계에서 손실은 다음과 같이 계산될 수 있습니다:
|
| 222 |
+
|
| 223 |
+
```py
|
| 224 |
+
>>> import torch.nn.functional as F
|
| 225 |
+
|
| 226 |
+
>>> noise_pred = model(noisy_image, timesteps).sample
|
| 227 |
+
>>> loss = F.mse_loss(noise_pred, noise)
|
| 228 |
+
```
|
| 229 |
+
|
| 230 |
+
## 모델 학습하기
|
| 231 |
+
|
| 232 |
+
지금까지, 모델 학습을 시작하기 위해 많은 부분을 갖추었으며 이제 남은 것은 모든 것을 조합하는 것입니다.
|
| 233 |
+
|
| 234 |
+
우선 옵티마이저(optimizer)와 학습률 스케줄러(learning rate scheduler)가 필요할 것입니다:
|
| 235 |
+
|
| 236 |
+
```py
|
| 237 |
+
>>> from diffusers.optimization import get_cosine_schedule_with_warmup
|
| 238 |
+
|
| 239 |
+
>>> optimizer = torch.optim.AdamW(model.parameters(), lr=config.learning_rate)
|
| 240 |
+
>>> lr_scheduler = get_cosine_schedule_with_warmup(
|
| 241 |
+
... optimizer=optimizer,
|
| 242 |
+
... num_warmup_steps=config.lr_warmup_steps,
|
| 243 |
+
... num_training_steps=(len(train_dataloader) * config.num_epochs),
|
| 244 |
+
... )
|
| 245 |
+
```
|
| 246 |
+
|
| 247 |
+
그 후, 모델을 평가하는 방법이 필요합니다. 평가를 위해, `DDPMPipeline`을 사용해 배치의 이미지 샘플들을 생성하고 그리드 형태로 저장할 수 있습니다:
|
| 248 |
+
|
| 249 |
+
```py
|
| 250 |
+
>>> from diffusers import DDPMPipeline
|
| 251 |
+
>>> import math
|
| 252 |
+
>>> import os
|
| 253 |
+
|
| 254 |
+
|
| 255 |
+
>>> def make_grid(images, rows, cols):
|
| 256 |
+
... w, h = images[0].size
|
| 257 |
+
... grid = Image.new("RGB", size=(cols * w, rows * h))
|
| 258 |
+
... for i, image in enumerate(images):
|
| 259 |
+
... grid.paste(image, box=(i % cols * w, i // cols * h))
|
| 260 |
+
... return grid
|
| 261 |
+
|
| 262 |
+
|
| 263 |
+
>>> def evaluate(config, epoch, pipeline):
|
| 264 |
+
... # 랜덤한 노이즈로 부터 이미지를 추출합니다.(이는 역전파 diffusion 과정입니다.)
|
| 265 |
+
... # 기본 파이프라인 출력 형태는 `List[PIL.Image]` 입니다.
|
| 266 |
+
... images = pipeline(
|
| 267 |
+
... batch_size=config.eval_batch_size,
|
| 268 |
+
... generator=torch.manual_seed(config.seed),
|
| 269 |
+
... ).images
|
| 270 |
+
|
| 271 |
+
... # 이미지들을 그리드로 만들어줍니다.
|
| 272 |
+
... image_grid = make_grid(images, rows=4, cols=4)
|
| 273 |
+
|
| 274 |
+
... # 이미지들을 저장합니다.
|
| 275 |
+
... test_dir = os.path.join(config.output_dir, "samples")
|
| 276 |
+
... os.makedirs(test_dir, exist_ok=True)
|
| 277 |
+
... image_grid.save(f"{test_dir}/{epoch:04d}.png")
|
| 278 |
+
```
|
| 279 |
+
|
| 280 |
+
TensorBoard에 로깅, 그래디언트 누적 및 혼합 정밀도 학습을 쉽게 수행하기 위해 🤗 Accelerate를 학습 루프에 함께 앞서 말한 모든 구성 정보들을 묶어 진행할 수 있습니다. 허브에 모델을 업로드 하기 위해 리포지토리 이름 및 정보를 가져오기 위한 함수를 작성하고 허브에 업로드할 수 있습니다.
|
| 281 |
+
|
| 282 |
+
💡아래의 학습 루프는 어렵고 길어 보일 수 있지만, 나중에 한 줄의 코드로 학습을 한다면 그만한 가치가 있을 것입니다! 만약 기다리지 못하고 이미지를 생성하고 싶다면, 아래 코드를 자유롭게 붙여넣고 작동시키면 됩니다. 🤗
|
| 283 |
+
|
| 284 |
+
```py
|
| 285 |
+
>>> from accelerate import Accelerator
|
| 286 |
+
>>> from huggingface_hub import create_repo, upload_folder
|
| 287 |
+
>>> from tqdm.auto import tqdm
|
| 288 |
+
>>> from pathlib import Path
|
| 289 |
+
>>> import os
|
| 290 |
+
|
| 291 |
+
|
| 292 |
+
>>> def train_loop(config, model, noise_scheduler, optimizer, train_dataloader, lr_scheduler):
|
| 293 |
+
... # Initialize accelerator and tensorboard logging
|
| 294 |
+
... accelerator = Accelerator(
|
| 295 |
+
... mixed_precision=config.mixed_precision,
|
| 296 |
+
... gradient_accumulation_steps=config.gradient_accumulation_steps,
|
| 297 |
+
... log_with="tensorboard",
|
| 298 |
+
... project_dir=os.path.join(config.output_dir, "logs"),
|
| 299 |
+
... )
|
| 300 |
+
... if accelerator.is_main_process:
|
| 301 |
+
... if config.output_dir is not None:
|
| 302 |
+
... os.makedirs(config.output_dir, exist_ok=True)
|
| 303 |
+
... if config.push_to_hub:
|
| 304 |
+
... repo_id = create_repo(
|
| 305 |
+
... repo_id=config.hub_model_id or Path(config.output_dir).name, exist_ok=True
|
| 306 |
+
... ).repo_id
|
| 307 |
+
... accelerator.init_trackers("train_example")
|
| 308 |
+
|
| 309 |
+
... # 모든 것이 준비되었습니다.
|
| 310 |
+
... # 기억해야 할 특정한 순서는 없으며 준비한 방법에 제공한 것과 동일한 순서로 객체의 압축을 풀면 됩니다.
|
| 311 |
+
... model, optimizer, train_dataloader, lr_scheduler = accelerator.prepare(
|
| 312 |
+
... model, optimizer, train_dataloader, lr_scheduler
|
| 313 |
+
... )
|
| 314 |
+
|
| 315 |
+
... global_step = 0
|
| 316 |
+
|
| 317 |
+
... # 이제 모델을 학습합니다.
|
| 318 |
+
... for epoch in range(config.num_epochs):
|
| 319 |
+
... progress_bar = tqdm(total=len(train_dataloader), disable=not accelerator.is_local_main_process)
|
| 320 |
+
... progress_bar.set_description(f"Epoch {epoch}")
|
| 321 |
+
|
| 322 |
+
... for step, batch in enumerate(train_dataloader):
|
| 323 |
+
... clean_images = batch["images"]
|
| 324 |
+
... # 이미지에 더할 노이즈를 샘플링합니다.
|
| 325 |
+
... noise = torch.randn(clean_images.shape, device=clean_images.device)
|
| 326 |
+
... bs = clean_images.shape[0]
|
| 327 |
+
|
| 328 |
+
... # 각 이미지를 위한 랜덤한 타임스텝(timestep)을 샘플링합니다.
|
| 329 |
+
... timesteps = torch.randint(
|
| 330 |
+
... 0, noise_scheduler.config.num_train_timesteps, (bs,), device=clean_images.device,
|
| 331 |
+
... dtype=torch.int64
|
| 332 |
+
... )
|
| 333 |
+
|
| 334 |
+
... # 각 타임스텝의 노이즈 크기에 따라 깨끗한 이미지에 노이즈를 추가합니다.
|
| 335 |
+
... # (이는 foward diffusion 과정입니다.)
|
| 336 |
+
... noisy_images = noise_scheduler.add_noise(clean_images, noise, timesteps)
|
| 337 |
+
|
| 338 |
+
... with accelerator.accumulate(model):
|
| 339 |
+
... # 노이즈를 반복적으로 예측합니다.
|
| 340 |
+
... noise_pred = model(noisy_images, timesteps, return_dict=False)[0]
|
| 341 |
+
... loss = F.mse_loss(noise_pred, noise)
|
| 342 |
+
... accelerator.backward(loss)
|
| 343 |
+
|
| 344 |
+
... accelerator.clip_grad_norm_(model.parameters(), 1.0)
|
| 345 |
+
... optimizer.step()
|
| 346 |
+
... lr_scheduler.step()
|
| 347 |
+
... optimizer.zero_grad()
|
| 348 |
+
|
| 349 |
+
... progress_bar.update(1)
|
| 350 |
+
... logs = {"loss": loss.detach().item(), "lr": lr_scheduler.get_last_lr()[0], "step": global_step}
|
| 351 |
+
... progress_bar.set_postfix(**logs)
|
| 352 |
+
... accelerator.log(logs, step=global_step)
|
| 353 |
+
... global_step += 1
|
| 354 |
+
|
| 355 |
+
... # 각 에포크가 끝난 후 evaluate()와 몇 가지 데모 이미지를 선택적으로 샘플링하고 모델을 저장합니다.
|
| 356 |
+
... if accelerator.is_main_process:
|
| 357 |
+
... pipeline = DDPMPipeline(unet=accelerator.unwrap_model(model), scheduler=noise_scheduler)
|
| 358 |
+
|
| 359 |
+
... if (epoch + 1) % config.save_image_epochs == 0 or epoch == config.num_epochs - 1:
|
| 360 |
+
... evaluate(config, epoch, pipeline)
|
| 361 |
+
|
| 362 |
+
... if (epoch + 1) % config.save_model_epochs == 0 or epoch == config.num_epochs - 1:
|
| 363 |
+
... if config.push_to_hub:
|
| 364 |
+
... upload_folder(
|
| 365 |
+
... repo_id=repo_id,
|
| 366 |
+
... folder_path=config.output_dir,
|
| 367 |
+
... commit_message=f"Epoch {epoch}",
|
| 368 |
+
... ignore_patterns=["step_*", "epoch_*"],
|
| 369 |
+
... )
|
| 370 |
+
... else:
|
| 371 |
+
... pipeline.save_pretrained(config.output_dir)
|
| 372 |
+
```
|
| 373 |
+
|
| 374 |
+
휴, 코드가 꽤 많았네요! 하지만 🤗 Accelerate의 [`~accelerate.notebook_launcher`] 함수와 학습을 시작할 준비가 되었습니다. 함수에 학습 루프, 모든 학습 인수, 학습에 사용할 프로세스 수(사용 가능한 GPU의 수를 변경할 수 있음)를 전달합니다:
|
| 375 |
+
|
| 376 |
+
```py
|
| 377 |
+
>>> from accelerate import notebook_launcher
|
| 378 |
+
|
| 379 |
+
>>> args = (config, model, noise_scheduler, optimizer, train_dataloader, lr_scheduler)
|
| 380 |
+
|
| 381 |
+
>>> notebook_launcher(train_loop, args, num_processes=1)
|
| 382 |
+
```
|
| 383 |
+
|
| 384 |
+
한번 학습이 완료되면, diffusion 모델로 생성된 최종 🦋이미지🦋를 확인해보길 바랍니다!
|
| 385 |
+
|
| 386 |
+
```py
|
| 387 |
+
>>> import glob
|
| 388 |
+
|
| 389 |
+
>>> sample_images = sorted(glob.glob(f"{config.output_dir}/samples/*.png"))
|
| 390 |
+
>>> Image.open(sample_images[-1])
|
| 391 |
+
```
|
| 392 |
+
|
| 393 |
+
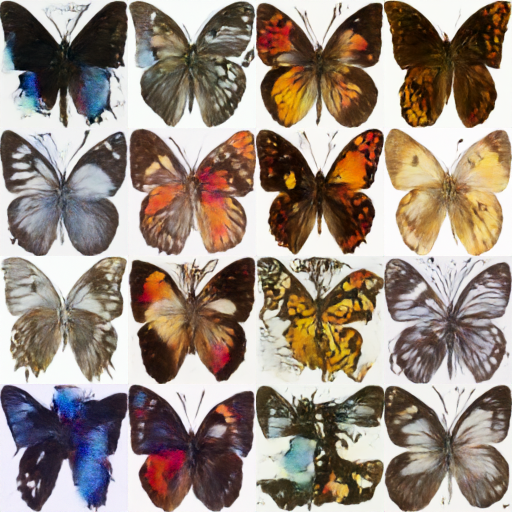
|
| 394 |
+
|
| 395 |
+
## 다음 단계
|
| 396 |
+
|
| 397 |
+
Unconditional 이미지 생성은 학습될 수 있는 작업 중 하나의 예시입니다. 다른 작업과 학습 방법은 [🧨 Diffusers 학습 예시](../training/overview) 페이지에서 확인할 수 있습니다. 다음은 학습할 수 있는 몇 가지 예시입니다:
|
| 398 |
+
|
| 399 |
+
- [Textual Inversion](../training/text_inversion), 특정 시각적 개념을 학습시켜 생성된 이미지에 통합시키는 알고리즘입니다.
|
| 400 |
+
- [DreamBooth](../training/dreambooth), 주제에 대한 몇 가지 입력 이미지들이 주어지면 주제에 대한 개인화된 이미지를 생성하기 위한 기술입니다.
|
| 401 |
+
- [Guide](../training/text2image) 데이터셋에 Stable Diffusion 모델을 파인튜닝하는 방법입니다.
|
| 402 |
+
- [Guide](../training/lora) LoRA를 사용해 매우 큰 모델을 빠르게 파인튜닝하기 위한 메모리 효율적인 기술입니다.
|
tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/tutorials/tutorial_overview.md
ADDED
|
@@ -0,0 +1,23 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2024 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Overview
|
| 14 |
+
|
| 15 |
+
🧨 Diffusers에 오신 걸 환영합니다! 여러분이 diffusion 모델과 생성 AI를 처음 접하고, 더 많은 걸 배우고 싶으셨다면 제대로 찾아오셨습니다. 이 튜토리얼은 diffusion model을 여러분에게 젠틀하게 소개하고, 라이브러리의 기본 사항(핵심 구성요소와 🧨 Diffusers 사용법)을 이해하는 데 도움이 되도록 설계되었습니다.
|
| 16 |
+
|
| 17 |
+
여러분은 이 튜토리얼을 통해 빠르게 생성하기 위해선 추론 파이프라인을 어떻게 사용해야 하는지, 그리고 라이브러리를 modular toolbox처럼 이용해서 여러분만의 diffusion system을 구축할 수 있도록 파이프라인을 분해하는 법을 배울 수 있습니다. 다음 단원에서는 여러분이 원하는 것을 생성하기 위해 자신만의 diffusion model을 학습하는 방법을 배우게 됩니다.
|
| 18 |
+
|
| 19 |
+
튜토리얼을 완료한다면 여러분은 라이브러리를 직접 탐색하고, 자신의 프로젝트와 애플리케이션에 적용할 스킬들을 습득할 수 있을 겁니다.
|
| 20 |
+
|
| 21 |
+
[Discord](https://discord.com/invite/JfAtkvEtRb)나 [포럼](https://discuss.huggingface.co/c/discussion-related-to-httpsgithubcomhuggingfacediffusers/63) 커뮤니티에 자유롭게 참여해서 다른 사용자와 개발자들과 교류하고 협업해 보세요!
|
| 22 |
+
|
| 23 |
+
자 지금부터 diffusing을 시작해 보겠습니다! 🧨
|
tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/using-diffusers/conditional_image_generation.md
ADDED
|
@@ -0,0 +1,60 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2024 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# 조건부 이미지 생성
|
| 14 |
+
|
| 15 |
+
[[open-in-colab]]
|
| 16 |
+
|
| 17 |
+
조건부 이미지 생성을 사용하면 텍스트 프롬프트에서 이미지를 생성할 수 있습니다. 텍스트는 임베딩으로 변환되며, 임베딩은 노이즈에서 이미지를 생성하도록 모델을 조건화하는 데 사용됩니다.
|
| 18 |
+
|
| 19 |
+
[`DiffusionPipeline`]은 추론을 위해 사전 훈련된 diffusion 시스템을 사용하는 가장 쉬운 방법입니다.
|
| 20 |
+
|
| 21 |
+
먼저 [`DiffusionPipeline`]의 인스턴스를 생성하고 다운로드할 파이프라인 [체크포인트](https://huggingface.co/models?library=diffusers&sort=downloads)를 지정합니다.
|
| 22 |
+
|
| 23 |
+
이 가이드에서는 [잠재 Diffusion](https://huggingface.co/CompVis/ldm-text2im-large-256)과 함께 텍스트-이미지 생성에 [`DiffusionPipeline`]을 사용합니다:
|
| 24 |
+
|
| 25 |
+
```python
|
| 26 |
+
>>> from diffusers import DiffusionPipeline
|
| 27 |
+
|
| 28 |
+
>>> generator = DiffusionPipeline.from_pretrained("CompVis/ldm-text2im-large-256")
|
| 29 |
+
```
|
| 30 |
+
|
| 31 |
+
[`DiffusionPipeline`]은 모든 모델링, 토큰화, 스케줄링 구성 요소를 다운로드하고 캐시합니다.
|
| 32 |
+
이 모델은 약 14억 개의 파라미터로 구성되어 있기 때문에 GPU에서 실행할 것을 강력히 권장합니다.
|
| 33 |
+
PyTorch에서와 마찬가지로 생성기 객체를 GPU로 이동할 수 있습니다:
|
| 34 |
+
|
| 35 |
+
```python
|
| 36 |
+
>>> generator.to("cuda")
|
| 37 |
+
```
|
| 38 |
+
|
| 39 |
+
이제 텍스트 프롬프트에서 `생성기`를 사용할 수 있습니다:
|
| 40 |
+
|
| 41 |
+
```python
|
| 42 |
+
>>> image = generator("An image of a squirrel in Picasso style").images[0]
|
| 43 |
+
```
|
| 44 |
+
|
| 45 |
+
출력값은 기본적으로 [`PIL.Image`](https://pillow.readthedocs.io/en/stable/reference/Image.html?highlight=image#the-image-class) 객체로 래핑됩니다.
|
| 46 |
+
|
| 47 |
+
호출하여 이미지를 저장할 수 있습니다:
|
| 48 |
+
|
| 49 |
+
```python
|
| 50 |
+
>>> image.save("image_of_squirrel_painting.png")
|
| 51 |
+
```
|
| 52 |
+
|
| 53 |
+
아래 스페이스를 사용해보고 안내 배율 매개변수를 자유롭게 조정하여 이미지 품질에 어떤 영향을 미치는지 확인해 보세요!
|
| 54 |
+
|
| 55 |
+
<iframe
|
| 56 |
+
src="https://stabilityai-stable-diffusion.hf.space"
|
| 57 |
+
frameborder="0"
|
| 58 |
+
width="850"
|
| 59 |
+
height="500"
|
| 60 |
+
></iframe>
|
tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/using-diffusers/controlling_generation.md
ADDED
|
@@ -0,0 +1,226 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2024 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# 제어된 생성
|
| 14 |
+
|
| 15 |
+
Diffusion 모델에 의해 생성된 출력을 제어하는 것은 커뮤니티에서 오랫동안 추구해 왔으며 현재 활발한 연구 주제입니다. 널리 사용되는 많은 diffusion 모델에서는 이미지와 텍스트 프롬프트 등 입력의 미묘한 변화로 인해 출력이 크게 달라질 수 있습니다. 이상적인 세계에서는 의미가 유지되고 변경되는 방식을 제어할 수 있기를 원합니다.
|
| 16 |
+
|
| 17 |
+
의미 보존의 대부분의 예는 입력의 변화를 출력의 변화에 정확하게 매핑하는 것으로 축소됩니다. 즉, 프롬프트에서 피사체에 형용사를 추가하면 전체 이미지가 보존되고 변경된 피사체만 수정됩니다. 또는 특정 피사체의 이미지를 변형하면 피사체의 포즈가 유지됩니다.
|
| 18 |
+
|
| 19 |
+
추가적으로 생성된 이미지의 품질에는 의미 보존 외에도 영향을 미치고자 하는 품질이 있습니다. 즉, 일반적으로 결과물의 품질이 좋거나 특정 스타일을 고수하거나 사실적이기를 원합니다.
|
| 20 |
+
|
| 21 |
+
diffusion 모델 생성을 제어하기 위해 `diffusers`가 지원하는 몇 가지 기술을 문서화합니다. 많은 부분이 최첨단 연구이며 미묘한 차이가 있을 수 있습니다. 명확한 설명이 필요하거나 제안 사항이 있으면 주저하지 마시고 [포럼](https://discuss.huggingface.co/) 또는 [GitHub 이슈](https://github.com/huggingface/diffusers/issues)에서 토론을 시작하세요.
|
| 22 |
+
|
| 23 |
+
생성 제어 방법에 대한 개략적인 설명과 기술 개요를 제공합니다. 기술에 대한 자세한 설명은 파이프라인에서 링크된 원본 논문을 참조하는 것이 가장 좋습니다.
|
| 24 |
+
|
| 25 |
+
사용 사례에 따라 적절한 기술을 선택해야 합니다. 많은 경우 이러한 기법을 결합할 수 있습니다. 예를 들어, 텍스트 반전과 SEGA를 결합하여 텍스트 반전을 사용하여 생성된 출력에 더 많은 의미적 지침을 제공할 수 있습니다.
|
| 26 |
+
|
| 27 |
+
별도의 언급이 없는 한, 이러한 기법은 기존 모델과 함께 작동하며 자체 가중치가 필요하지 않은 기법입니다.
|
| 28 |
+
|
| 29 |
+
1. [Instruct Pix2Pix](#instruct-pix2pix)
|
| 30 |
+
2. [Pix2Pix Zero](#pix2pixzero)
|
| 31 |
+
3. [Attend and Excite](#attend-and-excite)
|
| 32 |
+
4. [Semantic Guidance](#semantic-guidance)
|
| 33 |
+
5. [Self-attention Guidance](#self-attention-guidance)
|
| 34 |
+
6. [Depth2Image](#depth2image)
|
| 35 |
+
7. [MultiDiffusion Panorama](#multidiffusion-panorama)
|
| 36 |
+
8. [DreamBooth](#dreambooth)
|
| 37 |
+
9. [Textual Inversion](#textual-inversion)
|
| 38 |
+
10. [ControlNet](#controlnet)
|
| 39 |
+
11. [Prompt Weighting](#prompt-weighting)
|
| 40 |
+
12. [Custom Diffusion](#custom-diffusion)
|
| 41 |
+
13. [Model Editing](#model-editing)
|
| 42 |
+
14. [DiffEdit](#diffedit)
|
| 43 |
+
15. [T2I-Adapter](#t2i-adapter)
|
| 44 |
+
|
| 45 |
+
편의를 위해, 추론만 하거나 파인튜닝/학습하는 방법에 대한 표를 제공합니다.
|
| 46 |
+
|
| 47 |
+
| **Method** | **Inference only** | **Requires training /<br> fine-tuning** | **Comments** |
|
| 48 |
+
| :-------------------------------------------------: | :----------------: | :-------------------------------------: | :---------------------------------------------------------------------------------------------: |
|
| 49 |
+
| [Instruct Pix2Pix](#instruct-pix2pix) | ✅ | ❌ | Can additionally be<br>fine-tuned for better <br>performance on specific <br>edit instructions. |
|
| 50 |
+
| [Pix2Pix Zero](#pix2pixzero) | ✅ | ❌ | |
|
| 51 |
+
| [Attend and Excite](#attend-and-excite) | ✅ | ❌ | |
|
| 52 |
+
| [Semantic Guidance](#semantic-guidance) | ✅ | ❌ | |
|
| 53 |
+
| [Self-attention Guidance](#self-attention-guidance) | ✅ | ❌ | |
|
| 54 |
+
| [Depth2Image](#depth2image) | ✅ | ❌ | |
|
| 55 |
+
| [MultiDiffusion Panorama](#multidiffusion-panorama) | ✅ | ❌ | |
|
| 56 |
+
| [DreamBooth](#dreambooth) | ❌ | ✅ | |
|
| 57 |
+
| [Textual Inversion](#textual-inversion) | ❌ | ✅ | |
|
| 58 |
+
| [ControlNet](#controlnet) | ✅ | ❌ | A ControlNet can be <br>trained/fine-tuned on<br>a custom conditioning. |
|
| 59 |
+
| [Prompt Weighting](#prompt-weighting) | ✅ | ❌ | |
|
| 60 |
+
| [Custom Diffusion](#custom-diffusion) | ❌ | ✅ | |
|
| 61 |
+
| [Model Editing](#model-editing) | ✅ | ❌ | |
|
| 62 |
+
| [DiffEdit](#diffedit) | ✅ | ❌ | |
|
| 63 |
+
| [T2I-Adapter](#t2i-adapter) | ✅ | ❌ | |
|
| 64 |
+
|
| 65 |
+
## Pix2Pix Instruct
|
| 66 |
+
|
| 67 |
+
[Paper](https://huggingface.co/papers/2211.09800)
|
| 68 |
+
|
| 69 |
+
[Instruct Pix2Pix](../api/pipelines/stable_diffusion/pix2pix) 는 입력 이미지 편집을 지원하기 위해 stable diffusion에서 미세-조정되었습니다. 이미지와 편집을 설명하는 프롬프트를 입력으로 받아 편집된 이미지를 출력합니다.
|
| 70 |
+
Instruct Pix2Pix는 [InstructGPT](https://openai.com/blog/instruction-following/)와 같은 프롬프트와 잘 작동하도록 명시적으로 훈련되었습니다.
|
| 71 |
+
|
| 72 |
+
사용 방법에 대한 자세한 내용은 [여기](../api/pipelines/stable_diffusion/pix2pix)를 참조하세요.
|
| 73 |
+
|
| 74 |
+
## Pix2Pix Zero
|
| 75 |
+
|
| 76 |
+
[Paper](https://huggingface.co/papers/2302.03027)
|
| 77 |
+
|
| 78 |
+
[Pix2Pix Zero](../api/pipelines/stable_diffusion/pix2pix_zero)를 사용하면 일반적인 이미지 의미를 유지하면서 한 개념이나 피사체가 다른 개념이나 피사체로 변환되도록 이미지를 수정할 수 있습니다.
|
| 79 |
+
|
| 80 |
+
노이즈 제거 프로세스는 한 개념적 임베딩에서 다른 개념적 임베딩으로 안내됩니다. 중간 잠복(intermediate latents)은 디노이징(denoising?) 프로세스 중에 최적화되어 참조 주의 지도(reference attention maps)를 향해 나아갑니다. 참조 주의 지도(reference attention maps)는 입력 이미지의 노이즈 제거(?) 프로세스에서 나온 것으로 의미 보존을 장려하는 데 사용됩니다.
|
| 81 |
+
|
| 82 |
+
Pix2Pix Zero는 합성 이미지와 실제 이미지를 편집하는 데 모두 사용할 수 있습니다.
|
| 83 |
+
|
| 84 |
+
- 합성 이미지를 편집하려면 먼저 캡션이 지정된 이미지를 생성합니다.
|
| 85 |
+
다음으로 편집할 컨셉과 새로운 타겟 컨셉에 대한 이미지 캡션을 생성합니다. 이를 위해 [Flan-T5](https://huggingface.co/docs/transformers/model_doc/flan-t5)와 같은 모델을 사용할 수 있습니다. 그런 다음 텍스트 인코더를 통해 소스 개념과 대상 개념 모두에 대한 "평균" 프롬프트 임베딩을 생성합니다. 마지막으로, 합성 이미지를 편집하기 위해 pix2pix-zero 알고리즘을 사용합니다.
|
| 86 |
+
- 실제 이미지를 편집하려면 먼저 [BLIP](https://huggingface.co/docs/transformers/model_doc/blip)과 같은 모델을 사용하여 이미지 캡션을 생성합니다. 그런 다음 프롬프트와 이미지에 ddim 반전을 적용하여 "역(inverse)" latents을 생성합니다. 이전과 마찬가지로 소스 및 대상 개념 모두에 대한 "평균(mean)" 프롬프트 임베딩이 생성되고 마지막으로 "역(inverse)" latents와 결합된 pix2pix-zero 알고리즘이 이미지를 편집하는 데 사용됩니다.
|
| 87 |
+
|
| 88 |
+
<Tip>
|
| 89 |
+
|
| 90 |
+
Pix2Pix Zero는 '제로 샷(zero-shot)' 이미지 편집이 가능한 최초의 모델입니다.
|
| 91 |
+
즉, 이 모델은 다음과 같이 일반 소비자용 GPU에서 1분 이내에 이미지를 편집할 수 있습니다(../api/pipelines/stable_diffusion/pix2pix_zero#usage-example).
|
| 92 |
+
|
| 93 |
+
</Tip>
|
| 94 |
+
|
| 95 |
+
위��서 언급했듯이 Pix2Pix Zero에는 특정 개념으로 세대를 유도하기 위해 (UNet, VAE 또는 텍스트 인코더가 아닌) latents을 최적화하는 기능이 포함되어 있습니다.즉, 전체 파이프라인에 표준 [StableDiffusionPipeline](../api/pipelines/stable_diffusion/text2img)보다 더 많은 메모리가 필요할 수 있습니다.
|
| 96 |
+
|
| 97 |
+
사용 방법에 대한 자세한 내용은 [여기](../api/pipelines/stable_diffusion/pix2pix_zero)를 참조하세요.
|
| 98 |
+
|
| 99 |
+
## Attend and Excite
|
| 100 |
+
|
| 101 |
+
[Paper](https://huggingface.co/papers/2301.13826)
|
| 102 |
+
|
| 103 |
+
[Attend and Excite](../api/pipelines/stable_diffusion/attend_and_excite)를 사용하면 프롬프트의 피사체가 최종 이미지에 충실하게 표현되도록 할 수 있습니다.
|
| 104 |
+
|
| 105 |
+
이미지에 존재해야 하는 프롬프트의 피사체에 해당하는 일련의 토큰 인덱스가 입력으로 제공됩니다. 노이즈 제거 중에 각 토큰 인덱스는 이미지의 최소 한 패치 이상에 대해 최소 주의 임계값을 갖도록 보장됩니다. 모든 피사체 토큰에 대해 주의 임계값이 통과될 때까지 노이즈 제거 프로세스 중에 중간 잠복기가 반복적으로 최적화되어 가장 소홀히 취급되는 피사체 토큰의 주의력을 강화합니다.
|
| 106 |
+
|
| 107 |
+
Pix2Pix Zero와 마찬가지로 Attend and Excite 역시 파이프라인에 미니 최적화 루프(사전 학습된 가중치를 그대로 둔 채)가 포함되며, 일반적인 'StableDiffusionPipeline'보다 더 많은 메모리가 필요할 수 있습니다.
|
| 108 |
+
|
| 109 |
+
사용 방법에 대한 자세한 내용은 [여기](../api/pipelines/stable_diffusion/attend_and_excite)를 참조하세요.
|
| 110 |
+
|
| 111 |
+
## Semantic Guidance (SEGA)
|
| 112 |
+
|
| 113 |
+
[Paper](https://huggingface.co/papers/2301.12247)
|
| 114 |
+
|
| 115 |
+
의미유도(SEGA)를 사용하면 이미지에서 하나 이상의 컨셉을 적용하거나 제거할 수 있습니다. 컨셉의 강도도 조절할 수 있습니다. 즉, 스마일 컨셉을 사용하여 인물 사진의 스마일을 점진적으로 늘리거나 줄일 수 있습니다.
|
| 116 |
+
|
| 117 |
+
분류기 무료 안내(classifier free guidance)가 빈 프롬프트 입력을 통해 안내를 제공하는 방식과 유사하게, SEGA는 개념 프롬프트에 대한 안내를 제공합니다. 이러한 개념 프롬프트는 여러 개를 동시에 적용할 수 있습니다. 각 개념 프롬프트는 안내가 긍정적으로 적용되는지 또는 부정적으로 적용되는지에 따라 해당 개념을 추가하거나 제거할 수 있습니다.
|
| 118 |
+
|
| 119 |
+
Pix2Pix Zero 또는 Attend and Excite와 달리 SEGA는 명시적인 그라데이션 기반 최적화를 수행하는 대신 확산 프로세스와 직접 상호 작용합니다.
|
| 120 |
+
|
| 121 |
+
사용 방법에 대한 자세한 내용은 [여기](../api/pipelines/semantic_stable_diffusion)를 참조하세요.
|
| 122 |
+
|
| 123 |
+
## Self-attention Guidance (SAG)
|
| 124 |
+
|
| 125 |
+
[Paper](https://huggingface.co/papers/2210.00939)
|
| 126 |
+
|
| 127 |
+
[자기 주의 안내](../api/pipelines/stable_diffusion/self_attention_guidance)는 이미지의 전반적인 품질을 개선합니다.
|
| 128 |
+
|
| 129 |
+
SAG는 고빈도 세부 정보를 기반으로 하지 않은 예측에서 완전히 조건화된 이미지에 이르기까지 가이드를 제공합니다. 고빈도 디테일은 UNet 자기 주의 맵에서 추출됩니다.
|
| 130 |
+
|
| 131 |
+
사용 방법에 대한 자세한 내용은 [여기](../api/pipelines/stable_diffusion/self_attention_guidance)를 참조하세요.
|
| 132 |
+
|
| 133 |
+
## Depth2Image
|
| 134 |
+
|
| 135 |
+
[Project](https://huggingface.co/stabilityai/stable-diffusion-2-depth)
|
| 136 |
+
|
| 137 |
+
[Depth2Image](../pipelines/stable_diffusion_2#depthtoimage)는 텍스트 안내 이미지 변화에 대한 시맨틱을 더 잘 보존하도록 안정적 확산에서 미세 조정되었습니다.
|
| 138 |
+
|
| 139 |
+
원본 이미지의 단안(monocular) 깊이 추정치를 조건으로 합니다.
|
| 140 |
+
|
| 141 |
+
사용 방법에 대한 자세한 내용은 [여기](../api/pipelines/stable_diffusion_2#depthtoimage)를 참조하세요.
|
| 142 |
+
|
| 143 |
+
<Tip>
|
| 144 |
+
|
| 145 |
+
InstructPix2Pix와 Pix2Pix Zero와 같은 방법의 중요한 차이점은 전자의 경우
|
| 146 |
+
는 사전 학습된 가중치를 미세 조정하는 반면, 후자는 그렇지 않다는 것입니다. 즉, 다음을 수행할 수 있습니다.
|
| 147 |
+
사용 가능한 모든 안정적 확산 모델에 Pix2Pix Zero를 적용할 수 있습니다.
|
| 148 |
+
|
| 149 |
+
</Tip>
|
| 150 |
+
|
| 151 |
+
## MultiDiffusion Panorama
|
| 152 |
+
|
| 153 |
+
[Paper](https://huggingface.co/papers/2302.08113)
|
| 154 |
+
|
| 155 |
+
MultiDiffusion은 사전 학습된 diffusion model을 통해 새로운 생성 프로세스를 정의합니다. 이 프로세스는 고품질의 다양한 이미지를 생성하는 데 쉽게 적용할 수 있는 여러 diffusion 생성 방법을 하나로 묶습니다. 결과는 원하는 종횡비(예: 파노라마) 및 타이트한 분할 마스크에서 바운딩 박스에 이르는 공간 안내 신호와 같은 사용자가 제공한 제어를 준수합니다.
|
| 156 |
+
[MultiDiffusion 파노라마](../api/pipelines/stable_diffusion/panorama)를 사용하면 임의의 종횡비(예: 파노라마)로 고품질 이미지를 생성할 수 있습니다.
|
| 157 |
+
|
| 158 |
+
파노라마 이미지를 생성하는 데 사용하는 방법에 대한 자세한 내���은 [여기](../api/pipelines/stable_diffusion/panorama)를 참조하세요.
|
| 159 |
+
|
| 160 |
+
## 나만의 모델 파인튜닝
|
| 161 |
+
|
| 162 |
+
사전 학습된 모델 외에도 Diffusers는 사용자가 제공한 데이터에 대해 모델을 파인튜닝할 수 있는 학습 스크립트가 있습니다.
|
| 163 |
+
|
| 164 |
+
## DreamBooth
|
| 165 |
+
|
| 166 |
+
[DreamBooth](../training/dreambooth)는 모델을 파인튜닝하여 새로운 주제에 대해 가르칩니다. 즉, 한 사람의 사진 몇 장을 사용하여 다양한 스타일로 그 사람의 이미지를 생성할 수 있습니다.
|
| 167 |
+
|
| 168 |
+
사용 방법에 대한 자세한 내용은 [여기](../training/dreambooth)를 참조하세요.
|
| 169 |
+
|
| 170 |
+
## Textual Inversion
|
| 171 |
+
|
| 172 |
+
[Textual Inversion](../training/text_inversion)은 모델을 파인튜닝하여 새로운 개념에 대해 학습시킵니다. 즉, 특정 스타일의 아트웍 사진 몇 장을 사용하여 해당 스타일의 이미지를 생성할 수 있습니다.
|
| 173 |
+
|
| 174 |
+
사용 방법에 대한 자세한 내용은 [여기](../training/text_inversion)를 참조하세요.
|
| 175 |
+
|
| 176 |
+
## ControlNet
|
| 177 |
+
|
| 178 |
+
[Paper](https://huggingface.co/papers/2302.05543)
|
| 179 |
+
|
| 180 |
+
[ControlNet](../api/pipelines/stable_diffusion/controlnet)은 추가 조건을 추가하는 보조 네트워크입니다.
|
| 181 |
+
가장자리 감지, 낙서, 깊이 맵, 의미적 세그먼트와 같은 다양한 조건에 대해 훈련된 8개의 표준 사전 훈련된 ControlNet이 있습니다,
|
| 182 |
+
깊이 맵, 시맨틱 세그먼테이션과 같은 다양한 조건으로 훈련된 8개의 표준 제어망이 있습니다.
|
| 183 |
+
|
| 184 |
+
사용 방법에 대한 자세한 내용은 [여기](../api/pipelines/stable_diffusion/controlnet)를 참조하세요.
|
| 185 |
+
|
| 186 |
+
## Prompt Weighting
|
| 187 |
+
|
| 188 |
+
프롬프트 가중치는 텍스트의 특정 부분에 더 많은 관심 가중치를 부여하는 간단한 기법입니다.
|
| 189 |
+
입력에 가중치를 부여하는 간단한 기법입니다.
|
| 190 |
+
|
| 191 |
+
자세한 설명과 예시는 [여기](../using-diffusers/weighted_prompts)를 참조하세요.
|
| 192 |
+
|
| 193 |
+
## Custom Diffusion
|
| 194 |
+
|
| 195 |
+
[Custom Diffusion](../training/custom_diffusion)은 사전 학습된 text-to-image 간 확산 모델의 교차 관심도 맵만 미세 조정합니다.
|
| 196 |
+
또한 textual inversion을 추가로 수행할 수 있습니다. 설계상 다중 개념 훈련을 지원합니다.
|
| 197 |
+
DreamBooth 및 Textual Inversion 마찬가지로, 사용자 지정 확산은 사전학습된 text-to-image diffusion 모델에 새로운 개념을 학습시켜 관심 있는 개념과 관련된 출력을 생성하는 데에도 사용됩니다.
|
| 198 |
+
|
| 199 |
+
자세한 설명은 [공식 문서](../training/custom_diffusion)를 참조하세요.
|
| 200 |
+
|
| 201 |
+
## Model Editing
|
| 202 |
+
|
| 203 |
+
[Paper](https://huggingface.co/papers/2303.08084)
|
| 204 |
+
|
| 205 |
+
[텍스트-이미지 모델 편집 파이프라인](../api/pipelines/model_editing)을 사용하면 사전학습된 text-to-image diffusion 모델이 입력 프롬프트에 있는 피사체에 대해 내릴 수 있는 잘못된 암시적 가정을 완화하는 데 도움이 됩니다.
|
| 206 |
+
예를 들어, 안정적 확산에 "A pack of roses"에 대한 이미지를 생성하라는 메시지를 표시하면 생성된 이미지의 장미는 빨간색일 가능성이 높습니다. 이 파이프라인은 이러한 가정을 변경하는 데 도움이 됩니다.
|
| 207 |
+
|
| 208 |
+
자세한 설명은 [공식 문서](../api/pipelines/model_editing)를 참조하세요.
|
| 209 |
+
|
| 210 |
+
## DiffEdit
|
| 211 |
+
|
| 212 |
+
[Paper](https://huggingface.co/papers/2210.11427)
|
| 213 |
+
|
| 214 |
+
[DiffEdit](../api/pipelines/diffedit)를 사용하면 원본 입력 이미지를 최대한 보존하면서 입력 프롬프트와 함께 입력 이미지의 의미론적 편집이 가능합니다.
|
| 215 |
+
|
| 216 |
+
|
| 217 |
+
자세한 설명은 [공식 문서](../api/pipelines/diffedit)를 참조하세요.
|
| 218 |
+
|
| 219 |
+
## T2I-Adapter
|
| 220 |
+
|
| 221 |
+
[Paper](https://huggingface.co/papers/2302.08453)
|
| 222 |
+
|
| 223 |
+
[T2I-어댑터](../api/pipelines/stable_diffusion/adapter)는 추가적인 조건을 추가하는 auxiliary 네트워크입니다.
|
| 224 |
+
가장자리 감지, 스케치, depth maps, semantic segmentations와 같은 다양한 조건에 대해 훈련된 8개의 표준 사전훈련된 adapter가 있습니다,
|
| 225 |
+
|
| 226 |
+
[공식 문서](api/pipelines/stable_diffusion/adapter)에서 사용 방법에 대한 정보를 참조하세요.
|
tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/using-diffusers/custom_pipeline_overview.md
ADDED
|
@@ -0,0 +1,56 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2024 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# 커스텀 파이프라인 불러오기
|
| 14 |
+
|
| 15 |
+
[[open-in-colab]]
|
| 16 |
+
|
| 17 |
+
커뮤니티 파이프라인은 논문에 명시된 원래의 구현체와 다른 형태로 구현된 모든 [`DiffusionPipeline`] 클래스를 의미합니다. (예를 들어, [`StableDiffusionControlNetPipeline`]는 ["Text-to-Image Generation with ControlNet Conditioning"](https://huggingface.co/papers/2302.05543) 해당) 이들은 추가 기능을 제공하거나 파이프라인의 원래 구현을 확장합니다.
|
| 18 |
+
|
| 19 |
+
[Speech to Image](https://github.com/huggingface/diffusers/tree/main/examples/community#speech-to-image) 또는 [Composable Stable Diffusion](https://github.com/huggingface/diffusers/tree/main/examples/community#composable-stable-diffusion) 과 같은 멋진 커뮤니티 파이프라인이 많이 있으며 [여기에서](https://github.com/huggingface/diffusers/tree/main/examples/community) 모든 공식 커뮤니티 파이프라인을 찾을 수 있습니다.
|
| 20 |
+
|
| 21 |
+
허브에서 커뮤니티 파이프라인을 로드하려면, 커뮤니티 파이프라인의 리포지토리 ID와 (파이프라인 가중치 및 구성 요소를 로드하려는) 모델의 리포지토리 ID를 인자로 전달해야 합니다. 예를 들어, 아래 예시에서는 `hf-internal-testing/diffusers-dummy-pipeline`에서 더미 파이프라인을 불러오고, `google/ddpm-cifar10-32`에서 파이프라인의 가중치와 컴포넌트들을 로드합니다.
|
| 22 |
+
|
| 23 |
+
<Tip warning={true}>
|
| 24 |
+
|
| 25 |
+
🔒 허깅 페이스 허브에서 커뮤니티 파이프라인을 불러오는 것은 곧 해당 코드가 안전하다고 신뢰하는 것입니다. 코드를 자동으로 불러오고 실행하기 앞서 반드시 온라인으로 해당 코드의 신뢰성을 검사하세요!
|
| 26 |
+
|
| 27 |
+
</Tip>
|
| 28 |
+
|
| 29 |
+
```py
|
| 30 |
+
from diffusers import DiffusionPipeline
|
| 31 |
+
|
| 32 |
+
pipeline = DiffusionPipeline.from_pretrained(
|
| 33 |
+
"google/ddpm-cifar10-32", custom_pipeline="hf-internal-testing/diffusers-dummy-pipeline"
|
| 34 |
+
)
|
| 35 |
+
```
|
| 36 |
+
|
| 37 |
+
공식 커뮤니티 파이프라인을 불러오는 것은 비슷하지만, 공식 리포지토리 ID에서 가중치를 불러오는 것과 더불어 해당 파이프라인 내의 컴포넌트를 직접 지정하는 것 역시 가능합니다. 아래 예제를 보면 커뮤니티 [CLIP Guided Stable Diffusion](https://github.com/huggingface/diffusers/tree/main/examples/community#clip-guided-stable-diffusion) 파이프라인을 로드할 때, 해당 파이프라인에서 사용할 `clip_model` 컴포넌트와 `feature_extractor` 컴포넌트를 직접 설정하는 것을 확인할 수 있습니다.
|
| 38 |
+
|
| 39 |
+
```py
|
| 40 |
+
from diffusers import DiffusionPipeline
|
| 41 |
+
from transformers import CLIPImageProcessor, CLIPModel
|
| 42 |
+
|
| 43 |
+
clip_model_id = "laion/CLIP-ViT-B-32-laion2B-s34B-b79K"
|
| 44 |
+
|
| 45 |
+
feature_extractor = CLIPImageProcessor.from_pretrained(clip_model_id)
|
| 46 |
+
clip_model = CLIPModel.from_pretrained(clip_model_id)
|
| 47 |
+
|
| 48 |
+
pipeline = DiffusionPipeline.from_pretrained(
|
| 49 |
+
"stable-diffusion-v1-5/stable-diffusion-v1-5",
|
| 50 |
+
custom_pipeline="clip_guided_stable_diffusion",
|
| 51 |
+
clip_model=clip_model,
|
| 52 |
+
feature_extractor=feature_extractor,
|
| 53 |
+
)
|
| 54 |
+
```
|
| 55 |
+
|
| 56 |
+
커뮤니티 파이프라인에 대한 자세한 내용은 [커뮤니티 파이프라인](https://github.com/huggingface/diffusers/blob/main/docs/source/en/using-diffusers/custom_pipeline_examples) 가이드를 살펴보세요. 커뮤니티 파이프라인 등록에 관심이 있는 경우 [커뮤니티 파이프라인에 기여하는 방법](https://github.com/huggingface/diffusers/blob/main/docs/source/en/using-diffusers/contribute_pipeline)에 대한 가이드를 확인하세요 !
|
tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/ko/using-diffusers/depth2img.md
ADDED
|
@@ -0,0 +1,57 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2024 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Text-guided depth-to-image 생성
|
| 14 |
+
|
| 15 |
+
[[open-in-colab]]
|
| 16 |
+
|
| 17 |
+
[`StableDiffusionDepth2ImgPipeline`]을 사용하면 텍스트 프롬프트와 초기 이미지를 전달하여 새 이미지의 생성을 조절할 수 있습니다. 또한 이미지 구조를 보존하기 위해 `depth_map`을 전달할 수도 있습니다. `depth_map`이 제공되지 않으면 파이프라인은 통합된 [depth-estimation model](https://github.com/isl-org/MiDaS)을 통해 자동으로 깊이를 예측합니다.
|
| 18 |
+
|
| 19 |
+
|
| 20 |
+
먼저 [`StableDiffusionDepth2ImgPipeline`]의 인스턴스를 생성합니다:
|
| 21 |
+
|
| 22 |
+
```python
|
| 23 |
+
import torch
|
| 24 |
+
import requests
|
| 25 |
+
from PIL import Image
|
| 26 |
+
|
| 27 |
+
from diffusers import StableDiffusionDepth2ImgPipeline
|
| 28 |
+
|
| 29 |
+
pipe = StableDiffusionDepth2ImgPipeline.from_pretrained(
|
| 30 |
+
"stabilityai/stable-diffusion-2-depth",
|
| 31 |
+
torch_dtype=torch.float16,
|
| 32 |
+
).to("cuda")
|
| 33 |
+
```
|
| 34 |
+
|
| 35 |
+
이제 프롬프트를 파이프라인에 전달합니다. 특정 단어가 이미지 생성을 가이드 하는것을 방지하기 위해 `negative_prompt`를 전달할 수도 있습니다:
|
| 36 |
+
|
| 37 |
+
```python
|
| 38 |
+
url = "http://images.cocodataset.org/val2017/000000039769.jpg"
|
| 39 |
+
init_image = Image.open(requests.get(url, stream=True).raw)
|
| 40 |
+
prompt = "two tigers"
|
| 41 |
+
n_prompt = "bad, deformed, ugly, bad anatomy"
|
| 42 |
+
image = pipe(prompt=prompt, image=init_image, negative_prompt=n_prompt, strength=0.7).images[0]
|
| 43 |
+
image
|
| 44 |
+
```
|
| 45 |
+
|
| 46 |
+
| Input | Output |
|
| 47 |
+
|---------------------------------------------------------------------------------|---------------------------------------------------------------------------------------------------------------------------------------|
|
| 48 |
+
| <img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/coco-cats.png" width="500"/> | <img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/depth2img-tigers.png" width="500"/> |
|
| 49 |
+
|
| 50 |
+
아래의 Spaces를 가지고 놀며 depth map이 있는 이미지와 없는 이미지의 차이가 있는지 확인해 보세요!
|
| 51 |
+
|
| 52 |
+
<iframe
|
| 53 |
+
src="https://radames-stable-diffusion-depth2img.hf.space"
|
| 54 |
+
frameborder="0"
|
| 55 |
+
width="850"
|
| 56 |
+
height="500"
|
| 57 |
+
></iframe>
|